mirror of
https://github.com/BerriAI/litellm.git
synced 2026-10-06 02:48:13 +00:00
Merge remote-tracking branch 'upstream/litellm_internal_staging' into litellm_staging_03_23_2026
# Conflicts: # model_prices_and_context_window.json # tests/test_litellm/llms/vertex_ai/multimodal_embeddings/test_vertex_ai_multimodal_embedding_transformation.py
This commit is contained in:
 Chesars
commit
ebe16072f2
4206 changed files with 172265 additions and 310713 deletions
|
|
@ -1,36 +0,0 @@
|
|||
{
|
||||
"permissions": {
|
||||
"allow": [
|
||||
"Bash(git show:*)",
|
||||
"Bash(git worktree add:*)",
|
||||
"Read(//Users/krrishdholakia/Documents/litellm/**)",
|
||||
"Read(//Users/krrishdholakia/Documents/litellm-claude-code-guardrails/litellm/types/**)",
|
||||
"Read(//Users/krrishdholakia/Documents/litellm-claude-code-guardrails/**)",
|
||||
"Read(//Users/krrishdholakia/Documents/litellm-claude-code-guardrails/litellm/**)",
|
||||
"Bash(python:*)",
|
||||
"Bash(python -c \"\nimport sys; sys.path.insert\\(0, ''.''\\)\nfrom litellm.proxy.guardrails.guardrail_hooks.claude_code.guardrail import ClaudeCodeGuardrail, HOSTED_TOOL_PREFIXES\nprint\\(''HOSTED_TOOL_PREFIXES:'', HOSTED_TOOL_PREFIXES\\)\nprint\\(''ClaudeCodeGuardrail imported OK''\\)\n\")",
|
||||
"Read(//Users/krrishdholakia/Documents/litellm-mcp-jwt-groups/litellm/proxy/**)",
|
||||
"Read(//Users/krrishdholakia/Documents/litellm-mcp-jwt-groups/**)",
|
||||
"Bash(poetry run pytest:*)",
|
||||
"Bash(git add:*)",
|
||||
"Bash(git commit:*)",
|
||||
"Bash(poetry run python:*)",
|
||||
"Bash(poetry run pip:*)",
|
||||
"Bash(git reset:*)",
|
||||
"Bash(git cherry-pick:*)",
|
||||
"Bash(git checkout:*)",
|
||||
"Read(//Users/krrishdholakia/Documents/litellm/litellm/proxy/guardrails/guardrail_hooks/**)",
|
||||
"Read(//Users/krrishdholakia/Documents/**)",
|
||||
"Bash(git -C /Users/krrishdholakia/Documents/litellm-mcp-user-permissions worktree list)",
|
||||
"Bash(ls:*)"
|
||||
],
|
||||
"additionalDirectories": [
|
||||
"/Users/krrishdholakia/Documents/litellm-mcp-group-plan/plan",
|
||||
"/Users/krrishdholakia/Documents/litellm-claude-code-guardrails/litellm/proxy/guardrails/guardrail_hooks/claude_code",
|
||||
"/Users/krrishdholakia/Documents/litellm-claude-code-guardrails/litellm/types",
|
||||
"/Users/krrishdholakia/Documents/litellm-claude-code-guardrails",
|
||||
"/Users/krrishdholakia/Documents/litellm-mcp-jwt-groups/litellm/proxy",
|
||||
"/Users/krrishdholakia/Documents/litellm-mcp-jwt-groups/tests/test_litellm/proxy/auth"
|
||||
]
|
||||
}
|
||||
}
|
||||
|
|
@ -1,17 +1,17 @@
|
|||
#!/usr/bin/env bash
|
||||
set -e
|
||||
|
||||
echo "[post-create] Installing poetry via pip"
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install poetry
|
||||
echo "[post-create] Installing uv"
|
||||
curl -LsSf https://astral.sh/uv/0.10.9/install.sh | env UV_NO_MODIFY_PATH=1 sh
|
||||
export PATH="$HOME/.local/bin:$PATH"
|
||||
|
||||
echo "[post-create] Installing Python dependencies (poetry)"
|
||||
poetry install --with dev --extras proxy
|
||||
echo "[post-create] Installing Python dependencies (uv)"
|
||||
uv sync --frozen --group proxy-dev --extra proxy
|
||||
|
||||
echo "[post-create] Generating Prisma client"
|
||||
poetry run prisma generate
|
||||
uv run --no-sync prisma generate
|
||||
|
||||
echo "[post-create] Installing npm dependencies"
|
||||
cd ui/litellm-dashboard && npm install --no-audit --no-fund
|
||||
cd ui/litellm-dashboard && npm ci
|
||||
|
||||
echo "[post-create] Done"
|
||||
echo "[post-create] Done"
|
||||
|
|
|
|||
|
|
@ -37,7 +37,7 @@ secret:
|
|||
- "docs/**"
|
||||
- "**/*.md"
|
||||
- "**/*.lock"
|
||||
- "poetry.lock"
|
||||
- "uv.lock"
|
||||
- "package-lock.json"
|
||||
|
||||
# Ignore security incidents with the SHA256 of the occurrence (false positives)
|
||||
|
|
|
|||
2
.github/ISSUE_TEMPLATE/config.yml
vendored
2
.github/ISSUE_TEMPLATE/config.yml
vendored
|
|
@ -1,7 +1,7 @@
|
|||
blank_issues_enabled: true
|
||||
contact_links:
|
||||
- name: Schedule Demo
|
||||
url: https://calendly.com/d/cx9p-5yf-2nm/litellm-introductions
|
||||
url: https://enterprise.litellm.ai/demo
|
||||
about: Speak directly with Krrish and Ishaan, the founders, to discuss issues, share feedback, or explore improvements for LiteLLM
|
||||
- name: Discord
|
||||
url: https://discord.com/invite/wuPM9dRgDw
|
||||
|
|
|
|||
19
.github/codeql/codeql-config.yml
vendored
19
.github/codeql/codeql-config.yml
vendored
|
|
@ -1,22 +1,21 @@
|
|||
name: "LiteLLM CodeQL config"
|
||||
|
||||
# Use security-extended suite instead of security-and-quality to avoid
|
||||
# result sets > 2 GiB on this codebase that cause fatal OOM failures.
|
||||
queries:
|
||||
- uses: security-extended
|
||||
- uses: security-and-quality
|
||||
|
||||
# These two queries are security queries included in security-extended that
|
||||
# individually produce result sets > 2 GiB on this codebase, causing fatal
|
||||
# OOM failures. Exclude them as a safety net until CI confirms they no longer
|
||||
# OOM; drop these exclusions in a follow-up once verified.
|
||||
# Known OOM queries on large Python codebases:
|
||||
# CodeQL builds a full data flow graph in memory. These two queries trace
|
||||
# sensitive data through every log call / regex pattern, causing combinatorial
|
||||
# path explosion on codebases with extensive logging like LiteLLM (>2 GiB
|
||||
# result sets). This is a known CodeQL scaling limitation, not a code issue.
|
||||
# Re-test periodically as CodeQL improves or the codebase refactors logging.
|
||||
query-filters:
|
||||
- exclude:
|
||||
id: py/clear-text-logging-sensitive-data # CWE-312 — > 2 GiB result set
|
||||
id: py/clear-text-logging-sensitive-data # CWE-312
|
||||
- exclude:
|
||||
id: py/polynomial-redos # CWE-730 — > 2 GiB result set
|
||||
id: py/polynomial-redos # CWE-730
|
||||
|
||||
paths-ignore:
|
||||
- tests
|
||||
- docs
|
||||
- "**/*.md"
|
||||
- litellm/proxy/_experimental/out
|
||||
|
|
|
|||
7
.github/pull_request_template.md
vendored
7
.github/pull_request_template.md
vendored
|
|
@ -32,6 +32,13 @@ If you're seeing a delay in your PR being merged, ping the LiteLLM Team on [Slac
|
|||
- [ ] **Merge / cherry-pick CI run**
|
||||
Links:
|
||||
|
||||
## Screenshots / Proof of Fix
|
||||
|
||||
<!-- Include screenshots, screen recordings, or log output demonstrating that your changes work as expected.
|
||||
For bug fixes: show reproduction before the fix and passing behavior after.
|
||||
For new features: show the feature working end-to-end.
|
||||
For UI changes: include before/after screenshots. -->
|
||||
|
||||
## Type
|
||||
|
||||
<!-- Select the type of Pull Request -->
|
||||
|
|
|
|||
BIN
.github/screenshots/after_org_assigned.png
vendored
Normal file
BIN
.github/screenshots/after_org_assigned.png
vendored
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 96 KiB |
BIN
.github/screenshots/after_org_detail.png
vendored
Normal file
BIN
.github/screenshots/after_org_detail.png
vendored
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 103 KiB |
BIN
.github/screenshots/before_403_error.png
vendored
Normal file
BIN
.github/screenshots/before_403_error.png
vendored
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 123 KiB |
BIN
.github/screenshots/before_no_org.png
vendored
Normal file
BIN
.github/screenshots/before_no_org.png
vendored
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 95 KiB |
40
.github/scripts/close_duplicate_issues.py
vendored
40
.github/scripts/close_duplicate_issues.py
vendored
|
|
@ -42,7 +42,9 @@ def gh(*args: str) -> str:
|
|||
def fetch_open_issues(repo: str | None) -> list[dict]:
|
||||
"""Fetch all open issues (excluding PRs) via gh api --paginate."""
|
||||
if repo:
|
||||
endpoint = f"repos/{repo}/issues?state=open&per_page=100&sort=created&direction=asc"
|
||||
endpoint = (
|
||||
f"repos/{repo}/issues?state=open&per_page=100&sort=created&direction=asc"
|
||||
)
|
||||
else:
|
||||
endpoint = "repos/{owner}/{repo}/issues?state=open&per_page=100&sort=created&direction=asc"
|
||||
cmd = ["api", "--paginate", endpoint]
|
||||
|
|
@ -71,7 +73,9 @@ def close_as_duplicate(
|
|||
repo_args = ["--repo", repo] if repo else []
|
||||
|
||||
if dry_run:
|
||||
print(f" [DRY RUN] Would close #{issue_number} as duplicate of #{duplicate_of}")
|
||||
print(
|
||||
f" [DRY RUN] Would close #{issue_number} as duplicate of #{duplicate_of}"
|
||||
)
|
||||
return
|
||||
|
||||
# Add comment
|
||||
|
|
@ -115,7 +119,9 @@ def find_duplicate(
|
|||
return None
|
||||
|
||||
|
||||
def scan_all(issues: list[dict], threshold: float, repo: str | None, dry_run: bool) -> int:
|
||||
def scan_all(
|
||||
issues: list[dict], threshold: float, repo: str | None, dry_run: bool
|
||||
) -> int:
|
||||
"""Compare every issue against all older issues. Returns count of duplicates found."""
|
||||
# Sort oldest first
|
||||
issues.sort(key=lambda i: i["number"])
|
||||
|
|
@ -144,7 +150,11 @@ def scan_all(issues: list[dict], threshold: float, repo: str | None, dry_run: bo
|
|||
|
||||
|
||||
def check_single(
|
||||
issue_number: int, issues: list[dict], threshold: float, repo: str | None, dry_run: bool
|
||||
issue_number: int,
|
||||
issues: list[dict],
|
||||
threshold: float,
|
||||
repo: str | None,
|
||||
dry_run: bool,
|
||||
) -> bool:
|
||||
"""Check a single issue against all older open issues. Returns True if duplicate found."""
|
||||
target = None
|
||||
|
|
@ -178,13 +188,23 @@ def check_single(
|
|||
|
||||
|
||||
def main() -> None:
|
||||
parser = argparse.ArgumentParser(description="Detect and close duplicate GitHub issues")
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Detect and close duplicate GitHub issues"
|
||||
)
|
||||
mode = parser.add_mutually_exclusive_group(required=True)
|
||||
mode.add_argument("--scan", action="store_true", help="Scan all open issues")
|
||||
mode.add_argument("--issue-number", type=int, help="Check a single issue number")
|
||||
parser.add_argument("--threshold", type=float, default=0.85, help="Similarity threshold (0-1)")
|
||||
parser.add_argument("--close", action="store_true", help="Actually close duplicates (default is dry-run)")
|
||||
parser.add_argument("--repo", type=str, help="Repository (owner/repo). Auto-detected if omitted.")
|
||||
parser.add_argument(
|
||||
"--threshold", type=float, default=0.85, help="Similarity threshold (0-1)"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--close",
|
||||
action="store_true",
|
||||
help="Actually close duplicates (default is dry-run)",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--repo", type=str, help="Repository (owner/repo). Auto-detected if omitted."
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
dry_run = not args.close
|
||||
|
|
@ -200,7 +220,9 @@ def main() -> None:
|
|||
count = scan_all(issues, args.threshold, args.repo, dry_run)
|
||||
print(f"\nTotal duplicates {'found' if dry_run else 'closed'}: {count}")
|
||||
else:
|
||||
found = check_single(args.issue_number, issues, args.threshold, args.repo, dry_run)
|
||||
found = check_single(
|
||||
args.issue_number, issues, args.threshold, args.repo, dry_run
|
||||
)
|
||||
sys.exit(0 if found else 0) # Always exit 0; finding no dup is not an error
|
||||
|
||||
|
||||
|
|
|
|||
20
.github/scripts/scan_keywords.py
vendored
20
.github/scripts/scan_keywords.py
vendored
|
|
@ -67,14 +67,13 @@ def send_webhook(webhook_url: str, payload: dict) -> None:
|
|||
def _excerpt(text: str, max_len: int = 400) -> str:
|
||||
if not text:
|
||||
return ""
|
||||
|
||||
|
||||
# Keep original formatting
|
||||
if len(text) <= max_len:
|
||||
return text
|
||||
return text[: max_len - 1] + "…"
|
||||
|
||||
|
||||
|
||||
def main() -> int:
|
||||
event = read_event_payload()
|
||||
if not event:
|
||||
|
|
@ -87,8 +86,19 @@ def main() -> int:
|
|||
|
||||
# Keywords from env or defaults
|
||||
keywords_env = os.environ.get("KEYWORDS", "")
|
||||
default_keywords = ["azure", "openai", "bedrock", "vertexai", "vertex ai", "anthropic"]
|
||||
keywords = [k.strip() for k in keywords_env.split(",")] if keywords_env else default_keywords
|
||||
default_keywords = [
|
||||
"azure",
|
||||
"openai",
|
||||
"bedrock",
|
||||
"vertexai",
|
||||
"vertex ai",
|
||||
"anthropic",
|
||||
]
|
||||
keywords = (
|
||||
[k.strip() for k in keywords_env.split(",")]
|
||||
if keywords_env
|
||||
else default_keywords
|
||||
)
|
||||
|
||||
matches = detect_keywords(combined_text, keywords)
|
||||
found = bool(matches)
|
||||
|
|
@ -129,5 +139,3 @@ def main() -> int:
|
|||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
|
||||
|
||||
|
|
|
|||
2
.github/workflows/check_duplicate_issues.yml
vendored
2
.github/workflows/check_duplicate_issues.yml
vendored
|
|
@ -39,7 +39,7 @@ jobs:
|
|||
if: github.event.action == 'opened'
|
||||
uses: actions/setup-python@a26af69be951a213d495a4c3e4e4022e16d87065 # v5.6.0
|
||||
with:
|
||||
python-version: "3.11"
|
||||
python-version: "3.12"
|
||||
|
||||
- name: Auto-close if high-confidence duplicate
|
||||
if: github.event.action == 'opened'
|
||||
|
|
|
|||
18
.github/workflows/codspeed.yml
vendored
18
.github/workflows/codspeed.yml
vendored
|
|
@ -34,13 +34,21 @@ jobs:
|
|||
with:
|
||||
python-version: "3.12"
|
||||
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
pip install -e "."
|
||||
pip install pytest pytest-codspeed==4.3.0
|
||||
- name: Set up uv
|
||||
uses: astral-sh/setup-uv@37802adc94f370d6bfd71619e3f0bf239e1f3b78 # v7
|
||||
with:
|
||||
version: "0.10.9"
|
||||
|
||||
- name: Run benchmarks
|
||||
uses: CodSpeedHQ/action@1c8ae4843586d3ba879736b7f6b7b0c990757fab # v4.12.1
|
||||
with:
|
||||
mode: simulation
|
||||
run: pytest tests/benchmarks/ --codspeed
|
||||
run: >
|
||||
env PYTEST_DISABLE_PLUGIN_AUTOLOAD=1
|
||||
uv run --frozen --no-default-groups
|
||||
--with pytest==8.3.5
|
||||
--with pytest-codspeed==4.3.0
|
||||
pytest
|
||||
-p pytest_codspeed.plugin
|
||||
tests/benchmarks/
|
||||
--codspeed
|
||||
|
|
|
|||
65
.github/workflows/create-release-branch.yml
vendored
Normal file
65
.github/workflows/create-release-branch.yml
vendored
Normal file
|
|
@ -0,0 +1,65 @@
|
|||
name: Create Release Branch
|
||||
|
||||
on:
|
||||
workflow_dispatch:
|
||||
inputs:
|
||||
tag:
|
||||
description: "Release tag (e.g. v1.83.0-stable) — branch will be named release/<tag>"
|
||||
required: true
|
||||
type: string
|
||||
commit_hash:
|
||||
description: "Full 40-char commit SHA the branch should point to"
|
||||
required: true
|
||||
type: string
|
||||
workflow_call:
|
||||
inputs:
|
||||
tag:
|
||||
description: "Release tag"
|
||||
required: true
|
||||
type: string
|
||||
commit_hash:
|
||||
description: "Full 40-char commit SHA the branch should point to"
|
||||
required: true
|
||||
type: string
|
||||
|
||||
permissions: {}
|
||||
|
||||
jobs:
|
||||
create-branch:
|
||||
name: Create Release Branch
|
||||
runs-on: ubuntu-latest
|
||||
permissions:
|
||||
contents: write
|
||||
steps:
|
||||
- name: Validate inputs
|
||||
env:
|
||||
TAG: ${{ inputs.tag }}
|
||||
COMMIT_HASH: ${{ inputs.commit_hash }}
|
||||
run: |
|
||||
if ! echo "${COMMIT_HASH}" | grep -qE '^[0-9a-f]{40}$'; then
|
||||
echo "::error::commit_hash must be a full 40-character commit SHA"
|
||||
exit 1
|
||||
fi
|
||||
if ! echo "${TAG}" | grep -qE '^v[0-9]+\.[0-9]+\.[0-9]+'; then
|
||||
echo "::error::tag must start with vX.Y.Z"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
- name: Create release branch
|
||||
env:
|
||||
TAG: ${{ inputs.tag }}
|
||||
COMMIT_HASH: ${{ inputs.commit_hash }}
|
||||
uses: actions/github-script@60a0d83039c74a4aee543508d2ffcb1c3799cdea # v7.0.1
|
||||
with:
|
||||
script: |
|
||||
const tag = process.env.TAG;
|
||||
const commitHash = process.env.COMMIT_HASH;
|
||||
const branchName = `release/${tag}`;
|
||||
|
||||
await github.rest.git.createRef({
|
||||
owner: context.repo.owner,
|
||||
repo: context.repo.repo,
|
||||
ref: `refs/heads/${branchName}`,
|
||||
sha: commitHash,
|
||||
});
|
||||
core.info(`Created branch ${branchName} at ${commitHash}`);
|
||||
42
.github/workflows/guard-main-branch.yml
vendored
Normal file
42
.github/workflows/guard-main-branch.yml
vendored
Normal file
|
|
@ -0,0 +1,42 @@
|
|||
name: Guard main branch
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches:
|
||||
- main
|
||||
merge_group:
|
||||
|
||||
permissions: {}
|
||||
|
||||
# DO NOT RENAME the job's `name:` — it is referenced by GitHub branch
|
||||
# protection as a required status check on `main`. Renaming silently
|
||||
# breaks the gate.
|
||||
jobs:
|
||||
guard:
|
||||
name: Verify PR source branch
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 2
|
||||
steps:
|
||||
- name: Reject merge_group events
|
||||
if: github.event_name == 'merge_group'
|
||||
run: |
|
||||
echo "::error::Merge queue is not supported for main. Disable merge queue or update this guard."
|
||||
exit 1
|
||||
- name: Check head branch name
|
||||
env:
|
||||
HEAD_REF: ${{ github.head_ref }}
|
||||
HEAD_REPO: ${{ github.event.pull_request.head.repo.full_name }}
|
||||
BASE_REPO: ${{ github.repository }}
|
||||
run: |
|
||||
echo "PR head repo: $HEAD_REPO"
|
||||
echo "PR head branch: $HEAD_REF"
|
||||
if [ "$HEAD_REPO" != "$BASE_REPO" ]; then
|
||||
echo "::error::PRs to main must originate from the canonical repository ($BASE_REPO), not a fork ($HEAD_REPO). External contributors should open PRs against the 'litellm_oss_branch' branch instead."
|
||||
exit 1
|
||||
fi
|
||||
if [ "$HEAD_REF" = "litellm_internal_staging" ] || [[ "$HEAD_REF" == litellm_hotfix_?* ]]; then
|
||||
echo "Allowed source branch."
|
||||
exit 0
|
||||
fi
|
||||
echo "::error::PRs to main must originate from 'litellm_internal_staging' or a 'litellm_hotfix_*' branch. Got: '$HEAD_REF'. If this is a contribution, retarget the PR against 'litellm_oss_branch' instead."
|
||||
exit 1
|
||||
|
|
@ -325,7 +325,7 @@ def run_tests(test_path: str = "tests/llm_translation/",
|
|||
|
||||
# Run pytest
|
||||
cmd = [
|
||||
"poetry", "run", "pytest", test_path,
|
||||
"uv", "run", "--no-sync", "pytest", test_path,
|
||||
f"--junitxml={junit_xml}",
|
||||
"-v",
|
||||
"--tb=short",
|
||||
|
|
@ -335,7 +335,7 @@ def run_tests(test_path: str = "tests/llm_translation/",
|
|||
|
||||
# Add timeout if pytest-timeout is installed
|
||||
try:
|
||||
subprocess.run(["poetry", "run", "python", "-c", "import pytest_timeout"],
|
||||
subprocess.run(["uv", "run", "--no-sync", "python", "-c", "import pytest_timeout"],
|
||||
capture_output=True, check=True)
|
||||
cmd.extend(["--timeout=300"])
|
||||
except:
|
||||
|
|
@ -436,4 +436,4 @@ if __name__ == "__main__":
|
|||
commit=args.commit
|
||||
)
|
||||
|
||||
sys.exit(exit_code)
|
||||
sys.exit(exit_code)
|
||||
|
|
|
|||
128
.github/workflows/test-code-quality.yml
vendored
Normal file
128
.github/workflows/test-code-quality.yml
vendored
Normal file
|
|
@ -0,0 +1,128 @@
|
|||
name: Code Quality Checks
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event.pull_request.number || github.ref }}
|
||||
cancel-in-progress: true
|
||||
|
||||
jobs:
|
||||
code-quality:
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 15
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955 # v4.3.0
|
||||
with:
|
||||
persist-credentials: false
|
||||
|
||||
- name: Checkout litellm-docs into docs/my-website (for documentation_tests)
|
||||
uses: actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955 # v4.3.0
|
||||
with:
|
||||
repository: BerriAI/litellm-docs
|
||||
path: docs/my-website
|
||||
persist-credentials: false
|
||||
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@a26af69be951a213d495a4c3e4e4022e16d87065 # v5.6.0
|
||||
with:
|
||||
python-version: "3.12"
|
||||
|
||||
- name: Set up uv
|
||||
uses: astral-sh/setup-uv@37802adc94f370d6bfd71619e3f0bf239e1f3b78 # v7
|
||||
with:
|
||||
version: "0.10.9"
|
||||
|
||||
- name: Cache uv dependencies
|
||||
uses: actions/cache@0057852bfaa89a56745cba8c7296529d2fc39830 # v4.3.0
|
||||
with:
|
||||
path: |
|
||||
~/.cache/uv
|
||||
.venv
|
||||
key: ${{ runner.os }}-uv-${{ hashFiles('uv.lock') }}
|
||||
restore-keys: |
|
||||
${{ runner.os }}-uv-
|
||||
|
||||
- name: Install dependencies
|
||||
run: uv sync --frozen --all-groups --all-extras
|
||||
|
||||
- name: check_licenses
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/check_licenses.py
|
||||
|
||||
- name: check_provider_folders_documented
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/check_provider_folders_documented.py
|
||||
|
||||
- name: router_code_coverage
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/router_code_coverage.py
|
||||
|
||||
- name: test_chat_completion_imports
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/test_chat_completion_imports.py
|
||||
|
||||
- name: info_log_check
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/info_log_check.py
|
||||
|
||||
- name: check_guardrail_apply_decorator
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/check_guardrail_apply_decorator.py
|
||||
|
||||
- name: test_ban_set_verbose
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/test_ban_set_verbose.py
|
||||
|
||||
- name: code_qa_check_tests
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/code_qa_check_tests.py
|
||||
|
||||
- name: check_get_model_cost_key_performance
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/check_get_model_cost_key_performance.py
|
||||
|
||||
- name: test_proxy_types_import
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/test_proxy_types_import.py
|
||||
|
||||
- name: callback_manager_test
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/callback_manager_test.py
|
||||
|
||||
- name: recursive_detector
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/recursive_detector.py
|
||||
|
||||
- name: test_router_strategy_async
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/test_router_strategy_async.py
|
||||
|
||||
- name: litellm_logging_code_coverage
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/litellm_logging_code_coverage.py
|
||||
|
||||
- name: ensure_async_clients_test
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/ensure_async_clients_test.py
|
||||
|
||||
- name: enforce_llms_folder_style
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/enforce_llms_folder_style.py
|
||||
|
||||
- name: prevent_key_leaks_in_exceptions
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/prevent_key_leaks_in_exceptions.py
|
||||
|
||||
- name: check_unsafe_enterprise_import
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/check_unsafe_enterprise_import.py
|
||||
|
||||
- name: ban_copy_deepcopy_kwargs
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/ban_copy_deepcopy_kwargs.py
|
||||
|
||||
- name: check_fastuuid_usage
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/check_fastuuid_usage.py
|
||||
|
||||
- name: memory_test
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/memory_test.py
|
||||
|
||||
- name: documentation_test_env_keys
|
||||
run: uv run --no-sync python ./tests/documentation_tests/test_env_keys.py
|
||||
|
||||
- name: documentation_test_router_settings
|
||||
run: uv run --no-sync python ./tests/documentation_tests/test_router_settings.py
|
||||
|
||||
- name: documentation_test_api_docs
|
||||
run: uv run --no-sync python ./tests/documentation_tests/test_api_docs.py
|
||||
6
.github/workflows/test-litellm-ui-build.yml
vendored
6
.github/workflows/test-litellm-ui-build.yml
vendored
|
|
@ -4,7 +4,11 @@ permissions:
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
jobs:
|
||||
build-ui:
|
||||
|
|
|
|||
39
.github/workflows/test-semgrep.yml
vendored
Normal file
39
.github/workflows/test-semgrep.yml
vendored
Normal file
|
|
@ -0,0 +1,39 @@
|
|||
name: Semgrep
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event.pull_request.number || github.ref }}
|
||||
cancel-in-progress: true
|
||||
|
||||
jobs:
|
||||
semgrep:
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 10
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955 # v4.3.0
|
||||
with:
|
||||
persist-credentials: false
|
||||
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@a26af69be951a213d495a4c3e4e4022e16d87065 # v5.6.0
|
||||
with:
|
||||
python-version: "3.12"
|
||||
|
||||
- name: Set up uv
|
||||
uses: astral-sh/setup-uv@37802adc94f370d6bfd71619e3f0bf239e1f3b78 # v7
|
||||
with:
|
||||
version: "0.10.9"
|
||||
|
||||
- name: Run Semgrep (custom rules)
|
||||
run: uv tool run --from 'semgrep==1.157.0' semgrep scan --config .semgrep/rules . --error
|
||||
3
.gitignore
vendored
3
.gitignore
vendored
|
|
@ -72,8 +72,7 @@ tests/local_testing/log.txt
|
|||
.codegpt
|
||||
litellm/proxy/_new_new_secret_config.yaml
|
||||
litellm/proxy/custom_guardrail.py
|
||||
.mypy_cache/*
|
||||
.mypy_cache/*
|
||||
**/.mypy_cache/
|
||||
litellm/proxy/application.log
|
||||
tests/llm_translation/vertex_test_account.json
|
||||
tests/llm_translation/test_vertex_key.json
|
||||
|
|
|
|||
5
.npmrc
Normal file
5
.npmrc
Normal file
|
|
@ -0,0 +1,5 @@
|
|||
# Supply-chain hardening
|
||||
# Packages needing lifecycle scripts: npm rebuild <pkg>
|
||||
ignore-scripts=true
|
||||
# Protects local npm install only — npm ci (used in CI) ignores this
|
||||
min-release-age=3d
|
||||
18
.semgrep/rules/security/no-claude-directory.yml
Normal file
18
.semgrep/rules/security/no-claude-directory.yml
Normal file
|
|
@ -0,0 +1,18 @@
|
|||
rules:
|
||||
- id: no-claude-directory-committed
|
||||
message: >
|
||||
.claude/ directory must not be committed to the repository.
|
||||
It contains local Claude Code settings (permissions, worktree paths) that are
|
||||
developer-machine-specific and may expose internal paths or credentials.
|
||||
Add .claude/ to .gitignore instead.
|
||||
severity: ERROR
|
||||
languages: [generic]
|
||||
paths:
|
||||
include:
|
||||
- "/.claude/**"
|
||||
- "/.claude/*"
|
||||
pattern-regex: '[\s\S]+'
|
||||
metadata:
|
||||
category: security
|
||||
tags: [supply-chain, secrets]
|
||||
confidence: HIGH
|
||||
32
AGENTS.md
32
AGENTS.md
|
|
@ -23,10 +23,11 @@ LiteLLM is a unified interface for 100+ LLMs that:
|
|||
|
||||
### Key Directories
|
||||
- `tests/` - Comprehensive test suites
|
||||
- `docs/my-website/` - Documentation website
|
||||
- `ui/litellm-dashboard/` - Admin dashboard UI
|
||||
- `enterprise/` - Enterprise-specific features
|
||||
|
||||
Documentation lives in the separate [BerriAI/litellm-docs](https://github.com/BerriAI/litellm-docs) repository and is served at [docs.litellm.ai](https://docs.litellm.ai).
|
||||
|
||||
## DEVELOPMENT GUIDELINES
|
||||
|
||||
### MAKING CODE CHANGES
|
||||
|
|
@ -51,7 +52,9 @@ LiteLLM is a unified interface for 100+ LLMs that:
|
|||
|
||||
### MAKING CODE CHANGES FOR THE UI (IGNORE FOR BACKEND)
|
||||
|
||||
1. **Tremor is DEPRECATED, do not use Tremor components in new features/changes**
|
||||
1. **Always use `antd` for new UI components — Tremor is DEPRECATED**
|
||||
- We are migrating off of `@tremor/react`. Do not introduce new `Badge`, `Text`, `Card`, `Grid`, `Title`, or other imports from `@tremor/react` in any new or modified file.
|
||||
- Use `antd` equivalents: `Tag` for labels, plain `<span>`/`<div>` with Tailwind classes (or `Typography.Text`) for text, `Card` from `antd`, etc. Note that `antd` has no `"yellow"` Tag color — use `"gold"` for amber/yellow.
|
||||
- The only exception is the Tremor Table component and its required Tremor Table sub components.
|
||||
|
||||
2. **Use Common Components as much as possible**:
|
||||
|
|
@ -121,7 +124,7 @@ LiteLLM supports MCP for agent workflows:
|
|||
|
||||
## RUNNING SCRIPTS
|
||||
|
||||
Use `poetry run python script.py` to run Python scripts in the project environment (for non-test files).
|
||||
Use `uv run python script.py` to run Python scripts in the project environment (for non-test files).
|
||||
|
||||
## GITHUB TEMPLATES
|
||||
|
||||
|
|
@ -216,8 +219,8 @@ When opening issues or pull requests, follow these templates:
|
|||
|
||||
## HELPFUL RESOURCES
|
||||
|
||||
- Main documentation: https://docs.litellm.ai/
|
||||
- Provider-specific docs in `docs/my-website/docs/providers/`
|
||||
- Main documentation: https://docs.litellm.ai/ (source: [BerriAI/litellm-docs](https://github.com/BerriAI/litellm-docs))
|
||||
- Provider-specific docs: https://docs.litellm.ai/docs/providers/
|
||||
- Admin UI for testing proxy features
|
||||
|
||||
## WHEN IN DOUBT
|
||||
|
|
@ -232,16 +235,16 @@ When opening issues or pull requests, follow these templates:
|
|||
|
||||
### Environment
|
||||
|
||||
- Poetry is installed in `~/.local/bin`; the update script ensures it is on `PATH`.
|
||||
- uv is installed in `~/.local/bin`; the update script ensures it is on `PATH`.
|
||||
- Python 3.12, Node 22 are pre-installed.
|
||||
- The virtual environment lives under `~/.cache/pypoetry/virtualenvs/`.
|
||||
- The project virtual environment lives under `.venv/`.
|
||||
|
||||
### Running the proxy server
|
||||
|
||||
Start the proxy with a config file:
|
||||
|
||||
```bash
|
||||
poetry run litellm --config dev_config.yaml --port 4000
|
||||
uv run litellm --config dev_config.yaml --port 4000
|
||||
```
|
||||
|
||||
The proxy takes ~15-20 seconds to fully start (it runs Prisma migrations on boot). Wait for `/health` to return before sending requests. Without a PostgreSQL `DATABASE_URL`, the proxy connects to a default Neon dev database embedded in the `litellm-proxy-extras` package.
|
||||
|
|
@ -250,17 +253,16 @@ The proxy takes ~15-20 seconds to fully start (it runs Prisma migrations on boot
|
|||
|
||||
See `CLAUDE.md` and the `Makefile` for standard commands. Key notes:
|
||||
|
||||
- `psycopg-binary` must be installed (`poetry run pip install psycopg-binary`) because the pytest-postgresql plugin requires it and the lock file only includes `psycopg` (no binary).
|
||||
- `openapi-core` must be installed (`poetry run pip install openapi-core`) for the OpenAPI compliance tests in `tests/test_litellm/interactions/`.
|
||||
- `uv sync --group proxy-dev --extra proxy` installs the Prisma and proxy-side test dependencies used by the standard local workflow.
|
||||
- The `--timeout` pytest flag is NOT available; don't pass it.
|
||||
- Unit tests: `poetry run pytest tests/test_litellm/ -x -vv -n 4`
|
||||
- Black `--check` may report pre-existing formatting issues; this does not block test runs.
|
||||
- If `poetry install` fails with "pyproject.toml changed significantly since poetry.lock was last generated", run `poetry lock` first to regenerate the lock file.
|
||||
- Unit tests: `uv run pytest tests/test_litellm/ -x -vv -n 4`
|
||||
- **Before committing, always run `uv run black .` to format your code.** Black formatting is enforced in CI.
|
||||
- If `uv sync` fails because the lockfile is outdated, run `uv lock` and retry.
|
||||
|
||||
### Lint
|
||||
|
||||
```bash
|
||||
cd litellm && poetry run ruff check .
|
||||
cd litellm && uv run ruff check .
|
||||
```
|
||||
|
||||
Ruff is the primary fast linter. For the full lint suite (including mypy, black, circular imports), run `make lint` per `CLAUDE.md`.
|
||||
|
|
@ -271,4 +273,4 @@ Ruff is the primary fast linter. For the full lint suite (including mypy, black,
|
|||
- The proxy at port 4000 serves a **pre-built** static UI from `litellm/proxy/_experimental/out/`. After making UI code changes, you must run `npm run build` in the dashboard directory and copy the output: `cp -r ui/litellm-dashboard/out/* litellm/proxy/_experimental/out/` for the proxy to serve the updated UI.
|
||||
- SVGs used as provider logos (loaded via `<img>` tags) must NOT use `fill="currentColor"` — replace with an explicit color like `#000000` or use the `-color` variant from lobehub icons, since CSS color inheritance does not work inside `<img>` elements.
|
||||
- Provider logos live in `ui/litellm-dashboard/public/assets/logos/` (source) and `litellm/proxy/_experimental/out/assets/logos/` (pre-built). Both locations must have the file for it to work in dev and proxy-served modes.
|
||||
- UI Vitest tests: `cd ui/litellm-dashboard && npx vitest run`
|
||||
- UI Vitest tests: `cd ui/litellm-dashboard && npx vitest run`
|
||||
|
|
|
|||
24
CLAUDE.md
24
CLAUDE.md
|
|
@ -2,12 +2,16 @@
|
|||
|
||||
This file provides guidance to Claude Code (claude.ai/code) when working with code in this repository.
|
||||
|
||||
## Documentation
|
||||
|
||||
Documentation lives in a separate repository: [BerriAI/litellm-docs](https://github.com/BerriAI/litellm-docs). It is served at [docs.litellm.ai](https://docs.litellm.ai). Do not create or edit documentation files in this repository — open doc PRs against `BerriAI/litellm-docs` instead.
|
||||
|
||||
## Development Commands
|
||||
|
||||
### Installation
|
||||
- `make install-dev` - Install core development dependencies
|
||||
- `make install-proxy-dev` - Install proxy development dependencies with full feature set
|
||||
- `make install-test-deps` - Install all test dependencies
|
||||
- `make install-test-deps` - Install the full local test environment and generate the Prisma client
|
||||
|
||||
### Testing
|
||||
- `make test` - Run all tests
|
||||
|
|
@ -20,13 +24,14 @@ This file provides guidance to Claude Code (claude.ai/code) when working with co
|
|||
- `make format` - Apply Black code formatting
|
||||
- `make lint-ruff` - Run Ruff linting only
|
||||
- `make lint-mypy` - Run MyPy type checking only
|
||||
- **Before committing, always run `uv run black .` to format your code.** Black formatting is enforced in CI.
|
||||
|
||||
### Single Test Files
|
||||
- `poetry run pytest tests/path/to/test_file.py -v` - Run specific test file
|
||||
- `poetry run pytest tests/path/to/test_file.py::test_function -v` - Run specific test
|
||||
- `uv run pytest tests/path/to/test_file.py -v` - Run specific test file
|
||||
- `uv run pytest tests/path/to/test_file.py::test_function -v` - Run specific test
|
||||
|
||||
### Running Scripts
|
||||
- `poetry run python script.py` - Run Python scripts (use for non-test files)
|
||||
- `uv run python script.py` - Run Python scripts (use for non-test files)
|
||||
|
||||
### GitHub Issue & PR Templates
|
||||
When contributing to the project, use the appropriate templates:
|
||||
|
|
@ -108,6 +113,9 @@ LiteLLM is a unified interface for 100+ LLM providers with two main components:
|
|||
### UI / Backend Consistency
|
||||
- When wiring a new UI entity type to an existing backend endpoint, verify the backend API contract (single value vs. array, required vs. optional params) and ensure the UI controls match — e.g., use a single-select dropdown when the backend accepts a single value, not a multi-select
|
||||
|
||||
### UI Component Library
|
||||
- **Always use `antd` for new UI components** — we are migrating off of `@tremor/react`. Do not introduce new `Badge`, `Text`, `Card`, `Grid`, `Title`, or other imports from `@tremor/react` in any new or modified file. Use `antd` equivalents: `Tag` for labels, `Typography.Text` / `Typography.Title` / `Typography.Paragraph` for textual content (avoid plain text-only `<span>`, `<p>`, `<h*>` when Typography fits), and `Card` from `antd`. Note that `antd` has no `"yellow"` Tag color — use `"gold"` for amber/yellow.
|
||||
|
||||
### MCP OAuth / OpenAPI Transport Mapping
|
||||
- `TRANSPORT.OPENAPI` is a UI-only concept. The backend only accepts `"http"`, `"sse"`, or `"stdio"`. Always map it to `"http"` before any API call (including pre-OAuth temp-session calls).
|
||||
- FastAPI validation errors return `detail` as an array of `{loc, msg, type}` objects. Error extractors must handle: array (map `.msg`), string, nested `{error: string}`, and fallback.
|
||||
|
|
@ -150,6 +158,14 @@ LiteLLM is a unified interface for 100+ LLM providers with two main components:
|
|||
- Optional features enabled via environment variables
|
||||
- Separate licensing and authentication for enterprise features
|
||||
|
||||
### CI Supply-Chain Safety
|
||||
- **Never pipe a remote script into a shell** (`curl ... | bash`, `wget ... | sh`). Download the artifact to a file, verify its SHA-256 checksum, then install.
|
||||
- **Pin every external tool to a specific version** with a full URL (not `latest` or `stable`). Unversioned downloads silently change under you.
|
||||
- **Verify checksums for all downloaded binaries.** Use the provider's official `.sha256` / `.sha256sum` sidecar file when available; otherwise compute and hardcode the digest.
|
||||
- **Prefer reusable CircleCI commands** (`commands:` section) so a tool is installed and verified in exactly one place, then referenced everywhere with `- install_<tool>` or `- wait_for_service`.
|
||||
- **Don't add tools just because they were there before.** Audit whether an external dependency is still needed. If it can be replaced with a shell one-liner or a tool already in the image, remove it.
|
||||
- These rules apply to every download in CI: binaries, install scripts, language version managers, package repos. No exceptions.
|
||||
|
||||
### HTTP Client Cache Safety
|
||||
- **Never close HTTP/SDK clients on cache eviction.** `LLMClientCache._remove_key()` must not call `close()`/`aclose()` on evicted clients — they may still be used by in-flight requests. Doing so causes `RuntimeError: Cannot send a request, as the client has been closed.` after the 1-hour TTL expires. Cleanup happens at shutdown via `close_litellm_async_clients()`.
|
||||
|
||||
|
|
|
|||
|
|
@ -122,9 +122,17 @@ Run all unit tests (uses parallel execution for speed):
|
|||
make test-unit
|
||||
```
|
||||
|
||||
If you're running broader test suites, proxy tests, or anything that touches PostgreSQL-backed fixtures/plugins, install the full local test environment first:
|
||||
|
||||
```bash
|
||||
make install-test-deps
|
||||
```
|
||||
|
||||
This syncs the locked test environment used across the repo, including `psycopg` v3 plus `psycopg-binary` (used by `pytest-postgresql`), `psycopg2-binary` (used by some proxy E2E tests), and a generated Prisma client for DB-backed proxy tests, so pytest startup matches CI without manual package installs.
|
||||
|
||||
Run specific test files:
|
||||
```bash
|
||||
poetry run pytest tests/test_litellm/test_your_file.py -v
|
||||
uv run pytest tests/test_litellm/test_your_file.py -v
|
||||
```
|
||||
|
||||
### Running Linting and Formatting Checks
|
||||
|
|
@ -149,6 +157,19 @@ Apply formatting (auto-fixes issues):
|
|||
make format
|
||||
```
|
||||
|
||||
> **Black formatting is enforced in CI.** All PRs must pass the Black formatting check.
|
||||
>
|
||||
> - **AI coding agents** (Claude Code, Copilot, Cursor, etc.): `AGENTS.md` and `CLAUDE.md` instruct agents to run `poetry run black .` before committing.
|
||||
> - **VS Code users**: Install the [Black Formatter extension](https://marketplace.visualstudio.com/items?itemName=ms-python.black-formatter) and enable format-on-save:
|
||||
> ```json
|
||||
> {
|
||||
> "[python]": {
|
||||
> "editor.defaultFormatter": "ms-python.black-formatter",
|
||||
> "editor.formatOnSave": true
|
||||
> }
|
||||
> }
|
||||
> ```
|
||||
|
||||
### CI Compatibility
|
||||
|
||||
To ensure your changes will pass CI, run the exact same checks locally:
|
||||
|
|
@ -172,7 +193,7 @@ Run `make help` to see all available commands:
|
|||
make help # Show all available commands
|
||||
make install-dev # Install development dependencies
|
||||
make install-proxy-dev # Install proxy development dependencies
|
||||
make install-test-deps # Install test dependencies (for running tests)
|
||||
make install-test-deps # Install the full local test environment
|
||||
make format # Apply Black code formatting
|
||||
make format-check # Check Black formatting (matches CI)
|
||||
make lint # Run all linting checks
|
||||
|
|
@ -234,7 +255,7 @@ To run the proxy server locally:
|
|||
make install-proxy-dev
|
||||
|
||||
# Start the proxy server
|
||||
poetry run litellm --config your_config.yaml
|
||||
uv run litellm --config your_config.yaml
|
||||
```
|
||||
|
||||
### Docker Development
|
||||
|
|
@ -319,4 +340,4 @@ Looking for ideas? Check out:
|
|||
- 🧪 Test coverage improvements
|
||||
- 🔌 New LLM provider integrations
|
||||
|
||||
Thank you for contributing to LiteLLM! 🚀
|
||||
Thank you for contributing to LiteLLM! 🚀
|
||||
|
|
|
|||
144
Dockerfile
144
Dockerfile
|
|
@ -1,59 +1,75 @@
|
|||
# Base image for building
|
||||
ARG LITELLM_BUILD_IMAGE=cgr.dev/chainguard/wolfi-base
|
||||
ARG LITELLM_BUILD_IMAGE=cgr.dev/chainguard/wolfi-base@sha256:a5a619c1793039dcf92f02178f37c94bb3d6001403716da59d6092dfe8d9b502
|
||||
|
||||
# Runtime image
|
||||
ARG LITELLM_RUNTIME_IMAGE=cgr.dev/chainguard/wolfi-base
|
||||
ARG LITELLM_RUNTIME_IMAGE=cgr.dev/chainguard/wolfi-base@sha256:a5a619c1793039dcf92f02178f37c94bb3d6001403716da59d6092dfe8d9b502
|
||||
ARG UV_IMAGE=ghcr.io/astral-sh/uv:0.10.9@sha256:10902f58a1606787602f303954cea099626a4adb02acbac4c69920fe9d278f82
|
||||
|
||||
FROM $UV_IMAGE AS uvbin
|
||||
|
||||
# Builder stage
|
||||
FROM $LITELLM_BUILD_IMAGE AS builder
|
||||
|
||||
# Set the working directory to /app
|
||||
WORKDIR /app
|
||||
|
||||
USER root
|
||||
|
||||
# Install build dependencies
|
||||
RUN apk add --no-cache bash gcc py3-pip python3 python3-dev openssl openssl-dev
|
||||
COPY --from=uvbin /uv /usr/local/bin/uv
|
||||
COPY --from=uvbin /uvx /usr/local/bin/uvx
|
||||
|
||||
RUN python -m pip install build
|
||||
RUN apk add --no-cache \
|
||||
bash \
|
||||
gcc \
|
||||
python3 \
|
||||
python3-dev \
|
||||
openssl \
|
||||
openssl-dev \
|
||||
nodejs \
|
||||
npm \
|
||||
libsndfile
|
||||
|
||||
# Copy the current directory contents into the container at /app
|
||||
ENV UV_PROJECT_ENVIRONMENT=/app/.venv \
|
||||
UV_LINK_MODE=copy \
|
||||
PATH="/app/.venv/bin:${PATH}"
|
||||
|
||||
# Copy dependency metadata first for layer caching
|
||||
COPY pyproject.toml uv.lock ./
|
||||
COPY enterprise/pyproject.toml enterprise/
|
||||
COPY litellm-proxy-extras/pyproject.toml litellm-proxy-extras/
|
||||
|
||||
# Install third-party dependencies (cached unless pyproject.toml/uv.lock change)
|
||||
RUN uv sync --frozen --no-install-project --no-install-workspace --no-default-groups --no-editable \
|
||||
--extra proxy \
|
||||
--extra proxy-runtime \
|
||||
--extra extra_proxy \
|
||||
--extra semantic-router \
|
||||
--python python3
|
||||
|
||||
# Copy full source tree
|
||||
COPY . .
|
||||
|
||||
# Build Admin UI
|
||||
# Convert Windows line endings to Unix and make executable
|
||||
# Build Admin UI before final sync
|
||||
RUN sed -i 's/\r$//' docker/build_admin_ui.sh && chmod +x docker/build_admin_ui.sh && ./docker/build_admin_ui.sh
|
||||
|
||||
# Build the package
|
||||
RUN rm -rf dist/* && python -m build
|
||||
# Install project and workspace packages (fast - deps already cached)
|
||||
RUN uv sync --frozen --no-default-groups --no-editable \
|
||||
--extra proxy \
|
||||
--extra proxy-runtime \
|
||||
--extra extra_proxy \
|
||||
--extra semantic-router \
|
||||
--python python3
|
||||
|
||||
# There should be only one wheel file now, assume the build only creates one
|
||||
RUN ls -1 dist/*.whl | head -1
|
||||
RUN prisma generate --schema=./schema.prisma
|
||||
|
||||
# Install the package
|
||||
RUN pip install dist/*.whl
|
||||
|
||||
# install dependencies as wheels
|
||||
RUN pip wheel --no-cache-dir --wheel-dir=/wheels/ -r requirements.txt
|
||||
|
||||
# ensure pyjwt is used, not jwt
|
||||
RUN pip uninstall jwt -y
|
||||
RUN pip uninstall PyJWT -y
|
||||
RUN pip install PyJWT==2.12.0 --no-cache-dir
|
||||
RUN sed -i 's/\r$//' docker/entrypoint.sh && chmod +x docker/entrypoint.sh && \
|
||||
sed -i 's/\r$//' docker/prod_entrypoint.sh && chmod +x docker/prod_entrypoint.sh
|
||||
|
||||
# Runtime stage
|
||||
FROM $LITELLM_RUNTIME_IMAGE AS runtime
|
||||
|
||||
# Ensure runtime stage runs as root
|
||||
USER root
|
||||
|
||||
# Install runtime dependencies (libsndfile needed for audio processing on ARM64)
|
||||
RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip libsndfile && \
|
||||
npm install -g npm@latest tar@7.5.11 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 && \
|
||||
# SECURITY FIX: npm bundles tar, glob, and brace-expansion at multiple nested
|
||||
# levels inside its dependency tree. `npm install -g <pkg>` only creates a
|
||||
# SEPARATE global package, it does NOT replace npm's internal copies.
|
||||
# We must find and replace EVERY copy inside npm's directory.
|
||||
RUN apk add --no-cache bash openssl tzdata nodejs npm python3 libsndfile supervisor && \
|
||||
npm install -g npm@11.12.1 tar@7.5.11 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 && \
|
||||
GLOBAL="$(npm root -g)" && \
|
||||
find "$GLOBAL/npm" -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
|
|
@ -70,73 +86,27 @@ RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip libsndfile
|
|||
find "$GLOBAL/npm" -type d -name "diff" -path "*/node_modules/diff" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/diff" "$d"; \
|
||||
done && \
|
||||
# SECURITY FIX: patch npm's own package.json metadata so scanners see the
|
||||
# actual installed versions instead of the stale declared dependencies.
|
||||
find /usr/local/lib /usr/lib -path "*/node_modules/npm/package.json" -exec \
|
||||
sed -i 's/"tar": "\^7\.5\.[0-9]*"/"tar": "^7.5.10"/g; s/"minimatch": "\^10\.[0-9.]*"/"minimatch": "^10.2.4"/g' {} + 2>/dev/null && \
|
||||
npm cache clean --force && \
|
||||
# Remove the apk-tracked npm so its stale SBOM metadata (tar 7.5.9) is
|
||||
# no longer visible to image scanners. The globally installed npm@latest
|
||||
# at /usr/local/lib/node_modules/npm/ remains fully functional.
|
||||
{ apk del --no-cache npm 2>/dev/null || true; }
|
||||
|
||||
WORKDIR /app
|
||||
# Copy the current directory contents into the container at /app
|
||||
COPY . .
|
||||
RUN ls -la /app
|
||||
ENV PATH="/app/.venv/bin:${PATH}"
|
||||
|
||||
# Copy the built wheel from the builder stage to the runtime stage; assumes only one wheel file is present
|
||||
COPY --from=builder /app/dist/*.whl .
|
||||
COPY --from=builder /wheels/ /wheels/
|
||||
COPY --from=builder /app /app
|
||||
# Prisma binaries live in $HOME/.cache (default prisma-python location),
|
||||
# which is /root/.cache here. Copy them from the builder so they survive
|
||||
# deployments that volume-mount /app/.cache (e.g. readOnlyRootFilesystem
|
||||
# + emptyDir) — otherwise the mount would shadow the baked-in query engine.
|
||||
COPY --from=builder /root/.cache /root/.cache
|
||||
|
||||
# Install the built wheel using pip; again using a wildcard if it's the only file
|
||||
RUN pip install *.whl /wheels/* --no-index --find-links=/wheels/ && rm -f *.whl && rm -rf /wheels
|
||||
|
||||
# Replace the nodejs-wheel-binaries bundled node with the system node (fixes CVE-2025-55130)
|
||||
RUN NODEJS_WHEEL_NODE=$(find /usr/lib -path "*/nodejs_wheel/bin/node" 2>/dev/null) && \
|
||||
if [ -n "$NODEJS_WHEEL_NODE" ]; then cp /usr/bin/node "$NODEJS_WHEEL_NODE"; fi
|
||||
|
||||
# Remove test files and keys from dependencies
|
||||
RUN find /usr/lib -type f -path "*/tornado/test/*" -delete && \
|
||||
find /usr/lib -type d -path "*/tornado/test" -delete
|
||||
|
||||
# SECURITY FIX: nodejs-wheel-binaries (pip package used by Prisma) bundles a complete
|
||||
# npm with old vulnerable deps at /usr/lib/python3.*/site-packages/nodejs_wheel/.
|
||||
# Patch every copy of tar, glob, and brace-expansion inside that tree.
|
||||
RUN GLOBAL="$(npm root -g)" && \
|
||||
[ -n "$GLOBAL" ] || { echo "ERROR: npm root -g returned empty; aborting"; exit 1; } && \
|
||||
find /usr/lib -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "glob" -path "*/node_modules/glob" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/glob" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "brace-expansion" -path "*/node_modules/@isaacs/brace-expansion" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/@isaacs/brace-expansion" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "minimatch" -path "*/node_modules/minimatch" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/minimatch" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "diff" -path "*/node_modules/diff" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/diff" "$d"; \
|
||||
done
|
||||
|
||||
# Install semantic_router and aurelio-sdk using script
|
||||
# Convert Windows line endings to Unix and make executable
|
||||
RUN sed -i 's/\r$//' docker/install_auto_router.sh && chmod +x docker/install_auto_router.sh && ./docker/install_auto_router.sh
|
||||
|
||||
# Generate prisma client using the correct schema
|
||||
RUN prisma generate --schema=./litellm/proxy/schema.prisma
|
||||
# Convert Windows line endings to Unix for entrypoint scripts
|
||||
RUN sed -i 's/\r$//' docker/entrypoint.sh && chmod +x docker/entrypoint.sh
|
||||
RUN sed -i 's/\r$//' docker/prod_entrypoint.sh && chmod +x docker/prod_entrypoint.sh
|
||||
RUN find /app/.venv -type f -path "*/tornado/test/*" -delete && \
|
||||
find /app/.venv -type d -path "*/tornado/test" -delete
|
||||
|
||||
EXPOSE 4000/tcp
|
||||
|
||||
RUN apk add --no-cache supervisor
|
||||
COPY docker/supervisord.conf /etc/supervisord.conf
|
||||
|
||||
ENTRYPOINT ["docker/prod_entrypoint.sh"]
|
||||
|
||||
# Append "--detailed_debug" to the end of CMD to view detailed debug logs
|
||||
CMD ["--port", "4000"]
|
||||
|
|
|
|||
|
|
@ -22,11 +22,11 @@ This file provides guidance to Gemini when working with code in this repository.
|
|||
- `make lint-mypy` - Run MyPy type checking only
|
||||
|
||||
### Single Test Files
|
||||
- `poetry run pytest tests/path/to/test_file.py -v` - Run specific test file
|
||||
- `poetry run pytest tests/path/to/test_file.py::test_function -v` - Run specific test
|
||||
- `uv run pytest tests/path/to/test_file.py -v` - Run specific test file
|
||||
- `uv run pytest tests/path/to/test_file.py::test_function -v` - Run specific test
|
||||
|
||||
### Running Scripts
|
||||
- `poetry run python script.py` - Run Python scripts (use for non-test files)
|
||||
- `uv run python script.py` - Run Python scripts (use for non-test files)
|
||||
|
||||
### GitHub Issue & PR Templates
|
||||
When contributing to the project, use the appropriate templates:
|
||||
|
|
@ -105,4 +105,4 @@ LiteLLM is a unified interface for 100+ LLM providers with two main components:
|
|||
### Enterprise Features
|
||||
- Enterprise-specific code in `enterprise/` directory
|
||||
- Optional features enabled via environment variables
|
||||
- Separate licensing and authentication for enterprise features
|
||||
- Separate licensing and authentication for enterprise features
|
||||
|
|
|
|||
88
Makefile
88
Makefile
|
|
@ -15,7 +15,7 @@ help:
|
|||
@echo " make install-proxy-dev - Install proxy development dependencies"
|
||||
@echo " make install-dev-ci - Install dev dependencies (CI-compatible, pins OpenAI)"
|
||||
@echo " make install-proxy-dev-ci - Install proxy dev dependencies (CI-compatible)"
|
||||
@echo " make install-test-deps - Install test dependencies"
|
||||
@echo " make install-test-deps - Install the full local test environment"
|
||||
@echo " make install-helm-unittest - Install helm unittest plugin"
|
||||
@echo " make format - Apply Black code formatting"
|
||||
@echo " make format-check - Check Black code formatting (matches CI)"
|
||||
|
|
@ -40,49 +40,44 @@ help:
|
|||
@echo " make test-integration - Run integration tests"
|
||||
@echo " make test-unit-helm - Run helm unit tests"
|
||||
|
||||
# Keep PIP simple for edge cases:
|
||||
PIP := $(shell command -v pip > /dev/null 2>&1 && echo "pip" || echo "python3 -m pip")
|
||||
UV := uv
|
||||
UV_RUN := $(UV) run --no-sync
|
||||
|
||||
# Show info
|
||||
info:
|
||||
@echo "PIP: $(PIP)"
|
||||
@echo "UV: $(UV)"
|
||||
|
||||
# Installation targets
|
||||
install-dev:
|
||||
poetry install --with dev
|
||||
$(UV) sync --frozen
|
||||
|
||||
install-proxy-dev:
|
||||
poetry install --with dev,proxy-dev --extras proxy
|
||||
$(UV) sync --frozen --group proxy-dev --extra proxy
|
||||
|
||||
# CI-compatible installations (matches GitHub workflows exactly)
|
||||
install-dev-ci:
|
||||
$(PIP) install openai==2.8.0
|
||||
poetry install --with dev
|
||||
$(PIP) install openai==2.8.0
|
||||
$(UV) sync --frozen
|
||||
|
||||
install-proxy-dev-ci:
|
||||
poetry install --with dev,proxy-dev --extras proxy
|
||||
$(PIP) install openai==2.8.0
|
||||
$(UV) sync --frozen --group proxy-dev --extra proxy
|
||||
|
||||
install-test-deps: install-proxy-dev
|
||||
poetry run $(PIP) install "pytest-retry==1.6.3"
|
||||
poetry run $(PIP) install pytest-xdist
|
||||
poetry run $(PIP) install openapi-core
|
||||
cd enterprise && poetry run $(PIP) install -e . && cd ..
|
||||
$(UV) sync --frozen --all-groups --all-extras
|
||||
$(UV_RUN) prisma generate --schema litellm/proxy/schema.prisma
|
||||
|
||||
install-helm-unittest:
|
||||
helm plugin install https://github.com/helm-unittest/helm-unittest --version v0.4.4 || echo "ignore error if plugin exists"
|
||||
|
||||
# Formatting
|
||||
format: install-dev
|
||||
cd litellm && poetry run black . && cd ..
|
||||
cd litellm && $(UV_RUN) black . && cd ..
|
||||
|
||||
format-check: install-dev
|
||||
cd litellm && poetry run black --check . && cd ..
|
||||
cd litellm && $(UV_RUN) black --check . && cd ..
|
||||
|
||||
# Linting targets
|
||||
lint-ruff: install-dev
|
||||
cd litellm && poetry run ruff check . && cd ..
|
||||
cd litellm && $(UV_RUN) ruff check . && cd ..
|
||||
|
||||
# faster linter for developing ...
|
||||
# inspiration from:
|
||||
|
|
@ -96,37 +91,36 @@ lint-format-changed: install-dev
|
|||
$$start = $$1; $$count = $$2 || 1; $$end = $$start + $$count - 1; \
|
||||
print "$$file:$$start:1-$$end:999\n"; \
|
||||
}' | \
|
||||
while read range; do \
|
||||
file="$${range%%:*}"; \
|
||||
lines="$${range#*:}"; \
|
||||
echo "Formatting $$file (lines $$lines)"; \
|
||||
poetry run ruff format --range "$$lines" "$$file"; \
|
||||
done
|
||||
while read range; do \
|
||||
file="$${range%%:*}"; \
|
||||
lines="$${range#*:}"; \
|
||||
echo "Formatting $$file (lines $$lines)"; \
|
||||
$(UV_RUN) ruff format --range "$$lines" "$$file"; \
|
||||
done
|
||||
|
||||
lint-ruff-dev: install-dev
|
||||
@tmpfile=$$(mktemp /tmp/ruff-dev.XXXXXX) && \
|
||||
cd litellm && \
|
||||
(poetry run ruff check . --output-format=pylint || true) > "$$tmpfile" && \
|
||||
poetry run diff-quality --violations=pylint "$$tmpfile" --compare-branch=origin/main && \
|
||||
($(UV_RUN) ruff check . --output-format=pylint || true) > "$$tmpfile" && \
|
||||
$(UV_RUN) diff-quality --violations=pylint "$$tmpfile" --compare-branch=origin/main && \
|
||||
cd .. ; \
|
||||
rm -f "$$tmpfile"
|
||||
|
||||
lint-ruff-FULL-dev: install-dev
|
||||
@files=$$(git diff --name-only origin/main -- '*.py'); \
|
||||
if [ -n "$$files" ]; then echo "$$files" | xargs poetry run ruff check; \
|
||||
if [ -n "$$files" ]; then echo "$$files" | xargs $(UV_RUN) ruff check; \
|
||||
else echo "No changed .py files to check."; fi
|
||||
|
||||
lint-mypy: install-dev
|
||||
poetry run $(PIP) install types-requests types-setuptools types-redis types-PyYAML
|
||||
cd litellm && poetry run mypy . --ignore-missing-imports && cd ..
|
||||
cd litellm && $(UV_RUN) mypy . --ignore-missing-imports && cd ..
|
||||
|
||||
lint-black: format-check
|
||||
|
||||
check-circular-imports: install-dev
|
||||
cd litellm && poetry run python ../tests/documentation_tests/test_circular_imports.py && cd ..
|
||||
cd litellm && $(UV_RUN) python ../tests/documentation_tests/test_circular_imports.py && cd ..
|
||||
|
||||
check-import-safety: install-dev
|
||||
@poetry run python -c "from litellm import *; print('[from litellm import *] OK! no issues!');" || (echo '🚨 import failed, this means you introduced unprotected imports! 🚨'; exit 1)
|
||||
@$(UV_RUN) python -c "from litellm import *; print('[from litellm import *] OK! no issues!');" || (echo '🚨 import failed, this means you introduced unprotected imports! 🚨'; exit 1)
|
||||
|
||||
# Combined linting (matches test-linting.yml workflow)
|
||||
lint: format-check lint-ruff lint-mypy check-circular-imports check-import-safety
|
||||
|
|
@ -135,46 +129,46 @@ lint: format-check lint-ruff lint-mypy check-circular-imports check-import-safet
|
|||
lint-dev: lint-format-changed lint-mypy check-circular-imports check-import-safety
|
||||
|
||||
# Testing targets
|
||||
test:
|
||||
poetry run pytest tests/
|
||||
test: install-test-deps
|
||||
$(UV_RUN) pytest tests/
|
||||
|
||||
test-unit: install-test-deps
|
||||
poetry run pytest tests/test_litellm -x -vv -n 4
|
||||
$(UV_RUN) pytest tests/test_litellm -x -vv -n 4
|
||||
|
||||
# Matrix test targets (matching CI workflow groups)
|
||||
test-unit-llms: install-test-deps
|
||||
poetry run pytest tests/test_litellm/llms --tb=short -vv -n 4 --durations=20
|
||||
$(UV_RUN) pytest tests/test_litellm/llms --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-proxy-guardrails: install-test-deps
|
||||
poetry run pytest tests/test_litellm/proxy/guardrails tests/test_litellm/proxy/management_endpoints tests/test_litellm/proxy/management_helpers --tb=short -vv -n 4 --durations=20
|
||||
$(UV_RUN) pytest tests/test_litellm/proxy/guardrails tests/test_litellm/proxy/management_endpoints tests/test_litellm/proxy/management_helpers --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-proxy-core: install-test-deps
|
||||
poetry run pytest tests/test_litellm/proxy/auth tests/test_litellm/proxy/client tests/test_litellm/proxy/db tests/test_litellm/proxy/hooks tests/test_litellm/proxy/policy_engine --tb=short -vv -n 4 --durations=20
|
||||
$(UV_RUN) pytest tests/test_litellm/proxy/auth tests/test_litellm/proxy/client tests/test_litellm/proxy/db tests/test_litellm/proxy/hooks tests/test_litellm/proxy/policy_engine --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-proxy-misc: install-test-deps
|
||||
poetry run pytest tests/test_litellm/proxy/_experimental tests/test_litellm/proxy/agent_endpoints tests/test_litellm/proxy/anthropic_endpoints tests/test_litellm/proxy/common_utils tests/test_litellm/proxy/discovery_endpoints tests/test_litellm/proxy/experimental tests/test_litellm/proxy/google_endpoints tests/test_litellm/proxy/health_endpoints tests/test_litellm/proxy/image_endpoints tests/test_litellm/proxy/middleware tests/test_litellm/proxy/openai_files_endpoint tests/test_litellm/proxy/pass_through_endpoints tests/test_litellm/proxy/prompts tests/test_litellm/proxy/public_endpoints tests/test_litellm/proxy/response_api_endpoints tests/test_litellm/proxy/spend_tracking tests/test_litellm/proxy/ui_crud_endpoints tests/test_litellm/proxy/vector_store_endpoints tests/test_litellm/proxy/test_*.py --tb=short -vv -n 4 --durations=20
|
||||
$(UV_RUN) pytest tests/test_litellm/proxy/_experimental tests/test_litellm/proxy/agent_endpoints tests/test_litellm/proxy/anthropic_endpoints tests/test_litellm/proxy/common_utils tests/test_litellm/proxy/discovery_endpoints tests/test_litellm/proxy/experimental tests/test_litellm/proxy/google_endpoints tests/test_litellm/proxy/health_endpoints tests/test_litellm/proxy/image_endpoints tests/test_litellm/proxy/middleware tests/test_litellm/proxy/openai_files_endpoint tests/test_litellm/proxy/pass_through_endpoints tests/test_litellm/proxy/prompts tests/test_litellm/proxy/public_endpoints tests/test_litellm/proxy/response_api_endpoints tests/test_litellm/proxy/spend_tracking tests/test_litellm/proxy/ui_crud_endpoints tests/test_litellm/proxy/vector_store_endpoints tests/test_litellm/proxy/test_*.py --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-integrations: install-test-deps
|
||||
poetry run pytest tests/test_litellm/integrations --tb=short -vv -n 4 --durations=20
|
||||
$(UV_RUN) pytest tests/test_litellm/integrations --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-core-utils: install-test-deps
|
||||
poetry run pytest tests/test_litellm/litellm_core_utils --tb=short -vv -n 2 --durations=20
|
||||
$(UV_RUN) pytest tests/test_litellm/litellm_core_utils --tb=short -vv -n 2 --durations=20
|
||||
|
||||
test-unit-other: install-test-deps
|
||||
poetry run pytest tests/test_litellm/caching tests/test_litellm/responses tests/test_litellm/secret_managers tests/test_litellm/vector_stores tests/test_litellm/a2a_protocol tests/test_litellm/anthropic_interface tests/test_litellm/completion_extras tests/test_litellm/containers tests/test_litellm/enterprise tests/test_litellm/experimental_mcp_client tests/test_litellm/google_genai tests/test_litellm/images tests/test_litellm/interactions tests/test_litellm/passthrough tests/test_litellm/router_strategy tests/test_litellm/router_utils tests/test_litellm/types --tb=short -vv -n 4 --durations=20
|
||||
$(UV_RUN) pytest tests/test_litellm/caching tests/test_litellm/responses tests/test_litellm/secret_managers tests/test_litellm/vector_stores tests/test_litellm/a2a_protocol tests/test_litellm/anthropic_interface tests/test_litellm/completion_extras tests/test_litellm/containers tests/test_litellm/enterprise tests/test_litellm/experimental_mcp_client tests/test_litellm/google_genai tests/test_litellm/images tests/test_litellm/interactions tests/test_litellm/passthrough tests/test_litellm/router_strategy tests/test_litellm/router_utils tests/test_litellm/types --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-root: install-test-deps
|
||||
poetry run pytest tests/test_litellm/test_*.py --tb=short -vv -n 4 --durations=20
|
||||
$(UV_RUN) pytest tests/test_litellm/test_*.py --tb=short -vv -n 4 --durations=20
|
||||
|
||||
# Proxy unit tests (tests/proxy_unit_tests split alphabetically)
|
||||
test-proxy-unit-a: install-test-deps
|
||||
poetry run pytest tests/proxy_unit_tests/test_[a-o]*.py --tb=short -vv -n 2 --durations=20
|
||||
$(UV_RUN) pytest tests/proxy_unit_tests/test_[a-o]*.py --tb=short -vv -n 2 --durations=20
|
||||
|
||||
test-proxy-unit-b: install-test-deps
|
||||
poetry run pytest tests/proxy_unit_tests/test_[p-z]*.py --tb=short -vv -n 2 --durations=20
|
||||
$(UV_RUN) pytest tests/proxy_unit_tests/test_[p-z]*.py --tb=short -vv -n 2 --durations=20
|
||||
|
||||
test-integration:
|
||||
poetry run pytest tests/ -k "not test_litellm"
|
||||
test-integration: install-test-deps
|
||||
$(UV_RUN) pytest tests/ -k "not test_litellm"
|
||||
|
||||
test-unit-helm: install-helm-unittest
|
||||
helm unittest -f 'tests/*.yaml' deploy/charts/litellm-helm
|
||||
|
|
@ -188,6 +182,6 @@ test-llm-translation-single: install-test-deps
|
|||
@echo "Running single LLM translation test file..."
|
||||
@if [ -z "$(FILE)" ]; then echo "Usage: make test-llm-translation-single FILE=test_filename.py"; exit 1; fi
|
||||
@mkdir -p test-results
|
||||
poetry run pytest tests/llm_translation/$(FILE) \
|
||||
$(UV_RUN) pytest tests/llm_translation/$(FILE) \
|
||||
--junitxml=test-results/junit.xml \
|
||||
-v --tb=short --maxfail=100 --timeout=300
|
||||
|
|
|
|||
202
README.md
202
README.md
|
|
@ -2,20 +2,24 @@
|
|||
🚅 LiteLLM
|
||||
</h1>
|
||||
<p align="center">
|
||||
<p align="center">Call 100+ LLMs in OpenAI format. [Bedrock, Azure, OpenAI, VertexAI, Anthropic, Groq, etc.]
|
||||
<p align="center">LiteLLM AI Gateway
|
||||
</p>
|
||||
<p align="center">Open Source AI Gateway for 100+ LLMs. Self-hosted. Enterprise-ready. Call any LLM in OpenAI format.</p>
|
||||
<p align="center">
|
||||
<a href="https://render.com/deploy?repo=https://github.com/BerriAI/litellm" target="_blank" rel="nofollow"><img src="https://render.com/images/deploy-to-render-button.svg" alt="Deploy to Render"></a>
|
||||
<a href="https://railway.app/template/HLP0Ub?referralCode=jch2ME">
|
||||
<img src="https://railway.app/button.svg" alt="Deploy on Railway">
|
||||
<a href="https://railway.com/deploy/RhvhdC?referralCode=7mRv9K&utm_medium=integration&utm_source=template&utm_campaign=generic">
|
||||
<img src="https://railway.com/button.svg" alt="Deploy on Railway">
|
||||
</a>
|
||||
</p>
|
||||
</p>
|
||||
<h4 align="center"><a href="https://docs.litellm.ai/docs/simple_proxy" target="_blank">LiteLLM Proxy Server (AI Gateway)</a> | <a href="https://docs.litellm.ai/docs/enterprise#hosted-litellm-proxy" target="_blank"> Hosted Proxy</a> | <a href="https://docs.litellm.ai/docs/enterprise"target="_blank">Enterprise Tier</a></h4>
|
||||
<h4 align="center"><a href="https://docs.litellm.ai/docs/simple_proxy" target="_blank">LiteLLM Proxy Server (AI Gateway)</a> | <a href="https://docs.litellm.ai/docs/enterprise#hosted-litellm-proxy" target="_blank"> Hosted Proxy</a> | <a href="https://litellm.ai/enterprise"target="_blank">Enterprise Tier</a> | <a href="https://www.litellm.ai/ai-gateway" target="_blank">Website</a></h4>
|
||||
<h4 align="center">
|
||||
<a href="https://pypi.org/project/litellm/" target="_blank">
|
||||
<img src="https://img.shields.io/pypi/v/litellm.svg" alt="PyPI Version">
|
||||
</a>
|
||||
<a href="https://github.com/BerriAI/litellm" target="_blank">
|
||||
<img src="https://img.shields.io/github/stars/BerriAI/litellm.svg?style=social" alt="GitHub Stars">
|
||||
</a>
|
||||
<a href="https://www.ycombinator.com/companies/berriai">
|
||||
<img src="https://img.shields.io/badge/Y%20Combinator-W23-orange?style=flat-square" alt="Y Combinator W23">
|
||||
</a>
|
||||
|
|
@ -35,8 +39,45 @@
|
|||
|
||||
<img width="2688" height="1600" alt="Group 7154 (1)" src="https://github.com/user-attachments/assets/c5ee0412-6fb5-4fb6-ab5b-bafae4209ca6" />
|
||||
|
||||
---
|
||||
|
||||
## Use LiteLLM for
|
||||
## What is LiteLLM
|
||||
|
||||
LiteLLM is an open source AI Gateway that gives you a single, unified interface to call 100+ LLM providers — OpenAI, Anthropic, Gemini, Bedrock, Azure, and more — using the OpenAI format.
|
||||
|
||||
Use it as a **Python SDK** for direct library integration, or deploy the **AI Gateway (Proxy Server)** as a centralized service for your team or organization.
|
||||
|
||||
[**Jump to LiteLLM Proxy (LLM Gateway) Docs**](https://docs.litellm.ai/docs/simple_proxy) <br>
|
||||
[**Jump to Supported LLM Providers**](https://docs.litellm.ai/docs/providers)
|
||||
|
||||
---
|
||||
|
||||
## Why LiteLLM
|
||||
|
||||
Managing LLM calls across providers gets complicated fast — different SDKs, auth patterns, request formats, and error types for every model. LiteLLM removes that friction:
|
||||
|
||||
- **Unified API** — one interface for 100+ LLMs, no provider-specific SDK juggling
|
||||
- **Drop-in OpenAI compatibility** — swap providers without rewriting your code
|
||||
- **Production-ready gateway** — virtual keys, spend tracking, guardrails, load balancing, and an admin dashboard out of the box
|
||||
- **8ms P95 latency** at 1k RPS ([benchmarks](https://docs.litellm.ai/docs/benchmarks))
|
||||
|
||||
### OSS Adopters
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td><img height="60" alt="Stripe" src="https://github.com/user-attachments/assets/f7296d4f-9fbd-460d-9d05-e4df31697c4b" /></td>
|
||||
<td><img height="60" alt="image" src="https://github.com/user-attachments/assets/436fca71-988b-40bb-b5fe-8450c80fdbd0" /></td>
|
||||
<td><img height="60" alt="Google ADK" src="https://github.com/user-attachments/assets/caf270a2-5aee-45c4-8222-41a2070c4f19" /></td>
|
||||
<td><img height="60" alt="Greptile" src="https://github.com/user-attachments/assets/0be4bd8a-7cfa-48d3-9090-f415fe948280" /></td>
|
||||
<td><img height="60" alt="OpenHands" src="https://github.com/user-attachments/assets/a6150c4c-149e-4cae-888b-8b92be6e003f" /></td>
|
||||
<td><h2>Netflix</h2></td>
|
||||
<td><img height="60" alt="OpenAI Agents SDK" src="https://github.com/user-attachments/assets/c02f7be0-8c2e-4d27-aea7-7c024bfaebc0" /></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
---
|
||||
|
||||
## Features
|
||||
|
||||
<details open>
|
||||
<summary><b>LLMs</b> - Call 100+ LLMs (Python SDK + AI Gateway)</summary>
|
||||
|
|
@ -46,7 +87,7 @@
|
|||
### Python SDK
|
||||
|
||||
```shell
|
||||
pip install litellm
|
||||
uv add litellm
|
||||
```
|
||||
|
||||
```python
|
||||
|
|
@ -68,7 +109,7 @@ response = completion(model="anthropic/claude-sonnet-4-20250514", messages=[{"ro
|
|||
[**Getting Started - E2E Tutorial**](https://docs.litellm.ai/docs/proxy/docker_quick_start) - Setup virtual keys, make your first request
|
||||
|
||||
```shell
|
||||
pip install 'litellm[proxy]'
|
||||
uv tool install 'litellm[proxy]'
|
||||
litellm --model gpt-4o
|
||||
```
|
||||
|
||||
|
|
@ -219,62 +260,7 @@ curl -X POST 'http://0.0.0.0:4000/v1/chat/completions' \
|
|||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## How to use LiteLLM
|
||||
|
||||
You can use LiteLLM through either the Proxy Server or Python SDK. Both gives you a unified interface to access multiple LLMs (100+ LLMs). Choose the option that best fits your needs:
|
||||
|
||||
<table style={{width: '100%', tableLayout: 'fixed'}}>
|
||||
<thead>
|
||||
<tr>
|
||||
<th style={{width: '14%'}}></th>
|
||||
<th style={{width: '43%'}}><strong><a href="https://docs.litellm.ai/docs/simple_proxy">LiteLLM AI Gateway</a></strong></th>
|
||||
<th style={{width: '43%'}}><strong><a href="https://docs.litellm.ai/docs/">LiteLLM Python SDK</a></strong></th>
|
||||
</tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
<tr>
|
||||
<td style={{width: '14%'}}><strong>Use Case</strong></td>
|
||||
<td style={{width: '43%'}}>Central service (LLM Gateway) to access multiple LLMs</td>
|
||||
<td style={{width: '43%'}}>Use LiteLLM directly in your Python code</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td style={{width: '14%'}}><strong>Who Uses It?</strong></td>
|
||||
<td style={{width: '43%'}}>Gen AI Enablement / ML Platform Teams</td>
|
||||
<td style={{width: '43%'}}>Developers building LLM projects</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td style={{width: '14%'}}><strong>Key Features</strong></td>
|
||||
<td style={{width: '43%'}}>Centralized API gateway with authentication and authorization, multi-tenant cost tracking and spend management per project/user, per-project customization (logging, guardrails, caching), virtual keys for secure access control, admin dashboard UI for monitoring and management</td>
|
||||
<td style={{width: '43%'}}>Direct Python library integration in your codebase, Router with retry/fallback logic across multiple deployments (e.g. Azure/OpenAI) - <a href="https://docs.litellm.ai/docs/routing">Router</a>, application-level load balancing and cost tracking, exception handling with OpenAI-compatible errors, observability callbacks (Lunary, MLflow, Langfuse, etc.)</td>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
|
||||
LiteLLM Performance: **8ms P95 latency** at 1k RPS (See benchmarks [here](https://docs.litellm.ai/docs/benchmarks))
|
||||
|
||||
[**Jump to LiteLLM Proxy (LLM Gateway) Docs**](https://docs.litellm.ai/docs/simple_proxy) <br>
|
||||
[**Jump to Supported LLM Providers**](https://docs.litellm.ai/docs/providers)
|
||||
|
||||
**Stable Release:** Use docker images with the `-stable` tag. These have undergone 12 hour load tests, before being published. [More information about the release cycle here](https://docs.litellm.ai/docs/proxy/release_cycle)
|
||||
|
||||
Support for more providers. Missing a provider or LLM Platform, raise a [feature request](https://github.com/BerriAI/litellm/issues/new?assignees=&labels=enhancement&projects=&template=feature_request.yml&title=%5BFeature%5D%3A+).
|
||||
|
||||
## OSS Adopters
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td><img height="60" alt="Stripe" src="https://github.com/user-attachments/assets/f7296d4f-9fbd-460d-9d05-e4df31697c4b" /></td>
|
||||
<td><img height="60" alt="Google ADK" src="https://github.com/user-attachments/assets/caf270a2-5aee-45c4-8222-41a2070c4f19" /></td>
|
||||
<td><img height="60" alt="Greptile" src="https://github.com/user-attachments/assets/0be4bd8a-7cfa-48d3-9090-f415fe948280" /></td>
|
||||
<td><img height="60" alt="OpenHands" src="https://github.com/user-attachments/assets/a6150c4c-149e-4cae-888b-8b92be6e003f" /></td>
|
||||
<td><h2>Netflix</h2></td>
|
||||
<td><img height="60" alt="OpenAI Agents SDK" src="https://github.com/user-attachments/assets/c02f7be0-8c2e-4d27-aea7-7c024bfaebc0" /></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
## Supported Providers ([Website Supported Models](https://models.litellm.ai/) | [Docs](https://docs.litellm.ai/docs/providers))
|
||||
### Supported Providers ([Website Supported Models](https://models.litellm.ai/) | [Docs](https://docs.litellm.ai/docs/providers))
|
||||
|
||||
| Provider | `/chat/completions` | `/messages` | `/responses` | `/embeddings` | `/image/generations` | `/audio/transcriptions` | `/audio/speech` | `/moderations` | `/batches` | `/rerank` |
|
||||
|-------------------------------------------------------------------------------------|---------------------|-------------|--------------|---------------|----------------------|-------------------------|-----------------|----------------|-----------|-----------|
|
||||
|
|
@ -381,28 +367,94 @@ Support for more providers. Missing a provider or LLM Platform, raise a [feature
|
|||
|
||||
[**Read the Docs**](https://docs.litellm.ai/docs/)
|
||||
|
||||
## Run in Developer mode
|
||||
### Services
|
||||
---
|
||||
|
||||
## Get Started
|
||||
|
||||
You can use LiteLLM through either the Proxy Server or Python SDK. Both give you a unified interface to access multiple LLMs (100+ LLMs). Choose the option that best fits your needs:
|
||||
|
||||
<table style={{width: '100%', tableLayout: 'fixed'}}>
|
||||
<thead>
|
||||
<tr>
|
||||
<th style={{width: '14%'}}></th>
|
||||
<th style={{width: '43%'}}><strong><a href="https://docs.litellm.ai/docs/simple_proxy">LiteLLM AI Gateway</a></strong></th>
|
||||
<th style={{width: '43%'}}><strong><a href="https://docs.litellm.ai/docs/">LiteLLM Python SDK</a></strong></th>
|
||||
</tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
<tr>
|
||||
<td style={{width: '14%'}}><strong>Use Case</strong></td>
|
||||
<td style={{width: '43%'}}>Central service (LLM Gateway) to access multiple LLMs</td>
|
||||
<td style={{width: '43%'}}>Use LiteLLM directly in your Python code</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td style={{width: '14%'}}><strong>Who Uses It?</strong></td>
|
||||
<td style={{width: '43%'}}>Gen AI Enablement / ML Platform Teams</td>
|
||||
<td style={{width: '43%'}}>Developers building LLM projects</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td style={{width: '14%'}}><strong>Key Features</strong></td>
|
||||
<td style={{width: '43%'}}>Centralized API gateway with authentication and authorization, multi-tenant cost tracking and spend management per project/user, per-project customization (logging, guardrails, caching), virtual keys for secure access control, admin dashboard UI for monitoring and management</td>
|
||||
<td style={{width: '43%'}}>Direct Python library integration in your codebase, Router with retry/fallback logic across multiple deployments (e.g. Azure/OpenAI) - <a href="https://docs.litellm.ai/docs/routing">Router</a>, application-level load balancing and cost tracking, exception handling with OpenAI-compatible errors, observability callbacks (Lunary, MLflow, Langfuse, etc.)</td>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
|
||||
**Stable Release:** Use docker images with the `-stable` tag. These have undergone 12 hour load tests, before being published. [More information about the release cycle here](https://docs.litellm.ai/docs/proxy/release_cycle)
|
||||
|
||||
Support for more providers. Missing a provider or LLM Platform, raise a [feature request](https://github.com/BerriAI/litellm/issues/new?assignees=&labels=enhancement&projects=&template=feature_request.yml&title=%5BFeature%5D%3A+).
|
||||
|
||||
### Run in Developer Mode
|
||||
#### Services
|
||||
1. Setup .env file in root
|
||||
2. Run dependant services `docker-compose up db prometheus`
|
||||
|
||||
### Backend
|
||||
#### Backend
|
||||
1. (In root) create virtual environment `python -m venv .venv`
|
||||
2. Activate virtual environment `source .venv/bin/activate`
|
||||
3. Install dependencies `pip install -e ".[all]"`
|
||||
4. `pip install prisma`
|
||||
3. Install dependencies `uv sync --all-extras --group proxy-dev`
|
||||
4. `uv run prisma generate`
|
||||
5. `prisma generate`
|
||||
6. Start proxy backend `python litellm/proxy/proxy_cli.py`
|
||||
|
||||
### Frontend
|
||||
#### Frontend
|
||||
1. Navigate to `ui/litellm-dashboard`
|
||||
2. Install dependencies `npm install`
|
||||
3. Run `npm run dev` to start the dashboard
|
||||
|
||||
### Verify Docker Image Signatures
|
||||
|
||||
All LiteLLM Docker images published to GHCR are signed with [cosign](https://docs.sigstore.dev/cosign/overview/). Every release is signed with the same key introduced in [commit `0112e53`](https://github.com/BerriAI/litellm/commit/0112e53046018d726492c814b3644b7d376029d0).
|
||||
|
||||
**Verify using the pinned commit hash (recommended):**
|
||||
|
||||
A commit hash is cryptographically immutable, so this is the strongest way to ensure you are using the original signing key:
|
||||
|
||||
```bash
|
||||
cosign verify \
|
||||
--key https://raw.githubusercontent.com/BerriAI/litellm/0112e53046018d726492c814b3644b7d376029d0/cosign.pub \
|
||||
ghcr.io/berriai/litellm:<release-tag>
|
||||
```
|
||||
|
||||
**Verify using a release tag (convenience):**
|
||||
|
||||
Tags are protected in this repository and resolve to the same key. This option is easier to read but relies on tag protection rules:
|
||||
|
||||
```bash
|
||||
cosign verify \
|
||||
--key https://raw.githubusercontent.com/BerriAI/litellm/<release-tag>/cosign.pub \
|
||||
ghcr.io/berriai/litellm:<release-tag>
|
||||
```
|
||||
|
||||
Replace `<release-tag>` with the version you are deploying (e.g. `v1.83.0-stable`).
|
||||
|
||||
---
|
||||
|
||||
# Enterprise
|
||||
For companies that need better security, user management and professional support
|
||||
|
||||
[Talk to founders](https://calendly.com/d/cx9p-5yf-2nm/litellm-introductions)
|
||||
[Get an Enterprise License](https://litellm.ai/enterprise)
|
||||
[Talk to founders](https://enterprise.litellm.ai/demo)
|
||||
|
||||
This covers:
|
||||
- ✅ **Features under the [LiteLLM Commercial License](https://docs.litellm.ai/docs/proxy/enterprise):**
|
||||
|
|
@ -418,7 +470,7 @@ We welcome contributions to LiteLLM! Whether you're fixing bugs, adding features
|
|||
|
||||
## Quick Start for Contributors
|
||||
|
||||
This requires poetry to be installed.
|
||||
This requires uv to be installed.
|
||||
|
||||
```bash
|
||||
git clone https://github.com/BerriAI/litellm.git
|
||||
|
|
@ -432,6 +484,8 @@ make format-check # Check formatting only
|
|||
|
||||
For detailed contributing guidelines, see [CONTRIBUTING.md](CONTRIBUTING.md).
|
||||
|
||||
> **📖 Contributing to documentation?** The LiteLLM docs have moved to a separate repository: [BerriAI/litellm-docs](https://github.com/BerriAI/litellm-docs). Please open doc PRs there. Docs are served at [docs.litellm.ai](https://docs.litellm.ai).
|
||||
|
||||
## Code Quality / Linting
|
||||
|
||||
LiteLLM follows the [Google Python Style Guide](https://google.github.io/styleguide/pyguide.html).
|
||||
|
|
@ -452,13 +506,8 @@ All these checks must pass before your PR can be merged.
|
|||
- [Schedule Demo 👋](https://calendly.com/d/4mp-gd3-k5k/berriai-1-1-onboarding-litellm-hosted-version)
|
||||
- [Community Discord 💭](https://discord.gg/wuPM9dRgDw)
|
||||
- [Community Slack 💭](https://www.litellm.ai/support)
|
||||
- Our numbers 📞 +1 (770) 8783-106 / +1 (412) 618-6238
|
||||
- Our emails ✉️ ishaan@berri.ai / krrish@berri.ai
|
||||
|
||||
# Why did we build this
|
||||
|
||||
- **Need for simplicity**: Our code started to get extremely complicated managing & translating calls between Azure, OpenAI and Cohere.
|
||||
|
||||
# Contributors
|
||||
|
||||
<!-- ALL-CONTRIBUTORS-LIST:START - Do not remove or modify this section -->
|
||||
|
|
@ -473,4 +522,3 @@ All these checks must pass before your PR can be merged.
|
|||
<a href="https://github.com/BerriAI/litellm/graphs/contributors">
|
||||
<img src="https://contrib.rocks/image?repo=BerriAI/litellm" />
|
||||
</a>
|
||||
|
||||
|
|
|
|||
|
|
@ -1,23 +1,234 @@
|
|||
import argparse
|
||||
import os
|
||||
import subprocess
|
||||
from pathlib import Path
|
||||
from datetime import datetime
|
||||
import testing.postgresql
|
||||
import re
|
||||
import shutil
|
||||
import subprocess
|
||||
import sys
|
||||
from datetime import datetime
|
||||
from pathlib import Path
|
||||
|
||||
import testing.postgresql
|
||||
|
||||
|
||||
def create_migration(migration_name: str = None):
|
||||
DESTRUCTIVE_PATTERN = re.compile(r"\bDROP\s+(COLUMN|TABLE|INDEX)\b", re.IGNORECASE)
|
||||
DEFAULT_BASE_BRANCH = "litellm_internal_staging"
|
||||
|
||||
|
||||
def _find_destructive_statements(sql: str) -> list:
|
||||
"""Return SQL lines containing DROP COLUMN, DROP TABLE, or DROP INDEX."""
|
||||
return [
|
||||
line.strip() for line in sql.splitlines() if DESTRUCTIVE_PATTERN.search(line)
|
||||
]
|
||||
|
||||
|
||||
def _print_freshness_failure(
|
||||
base_branch: str, reason: str, stderr_text: str = ""
|
||||
) -> None:
|
||||
"""Loudly refuse to run when the freshness check can't be completed."""
|
||||
banner = "=" * 72
|
||||
out = sys.stderr
|
||||
print(banner, file=out)
|
||||
print(f" FRESHNESS CHECK FAILED — COULD NOT VERIFY origin/{base_branch}", file=out)
|
||||
print(banner, file=out)
|
||||
print("", file=out)
|
||||
print(f"Reason: {reason}", file=out)
|
||||
if stderr_text:
|
||||
print("", file=out)
|
||||
print("git stderr:", file=out)
|
||||
for line in stderr_text.rstrip().splitlines():
|
||||
print(f" {line}", file=out)
|
||||
print("", file=out)
|
||||
print("Common causes:", file=out)
|
||||
print(" - No network access (offline)", file=out)
|
||||
print(" - 'origin' remote not configured, or base branch name is wrong", file=out)
|
||||
print(" - Not a git repository", file=out)
|
||||
print("", file=out)
|
||||
print("Options:", file=out)
|
||||
print(
|
||||
f" - Fix the above and re-run, OR pass --base-branch <name> if your", file=out
|
||||
)
|
||||
print(
|
||||
f" base branch is not '{base_branch}', OR pass --skip-freshness-check",
|
||||
file=out,
|
||||
)
|
||||
print(" to bypass (only if you fully understand the risk).", file=out)
|
||||
print(banner, file=out)
|
||||
|
||||
|
||||
def _print_stale_branch_refusal(base_branch: str, behind: int) -> None:
|
||||
"""Loudly refuse to run when HEAD is behind the base branch."""
|
||||
banner = "=" * 72
|
||||
out = sys.stderr
|
||||
print(banner, file=out)
|
||||
print(
|
||||
f" STALE BRANCH — {behind} commit(s) behind origin/{base_branch}",
|
||||
file=out,
|
||||
)
|
||||
print(banner, file=out)
|
||||
print("", file=out)
|
||||
print(
|
||||
f"Your branch is {behind} commit(s) behind origin/{base_branch}. Generating a\n"
|
||||
"migration from a stale branch is how newly-added columns get silently\n"
|
||||
"dropped — the exact incident this guard exists to prevent.",
|
||||
file=out,
|
||||
)
|
||||
print("", file=out)
|
||||
print("Before re-running:", file=out)
|
||||
print(f" git fetch origin && git rebase origin/{base_branch}", file=out)
|
||||
print(" # or merge, whichever matches your workflow", file=out)
|
||||
print("", file=out)
|
||||
print(
|
||||
"If you have a genuine reason to bypass (e.g. intentionally generating",
|
||||
file=out,
|
||||
)
|
||||
print("a migration against an older base), pass --skip-freshness-check.", file=out)
|
||||
print("", file=out)
|
||||
print(banner, file=out)
|
||||
print(
|
||||
" AI AGENTS / ASSISTANTS: DO NOT automatically run `git rebase` or pass\n"
|
||||
" --skip-freshness-check. Surface this error to the human operator and\n"
|
||||
" wait for their explicit confirmation. Auto-rebasing can drop the\n"
|
||||
" human's in-progress schema edits via a bad conflict resolution.",
|
||||
file=out,
|
||||
)
|
||||
print(banner, file=out)
|
||||
|
||||
|
||||
def _check_branch_freshness(root_dir: Path, base_branch: str) -> None:
|
||||
"""Fetch origin/<base_branch> and exit 3 if HEAD is behind it."""
|
||||
cwd = str(root_dir)
|
||||
try:
|
||||
subprocess.run(
|
||||
["git", "fetch", "origin", base_branch],
|
||||
check=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
cwd=cwd,
|
||||
)
|
||||
except FileNotFoundError:
|
||||
_print_freshness_failure(base_branch, "git executable not found on PATH")
|
||||
sys.exit(3)
|
||||
except subprocess.CalledProcessError as e:
|
||||
_print_freshness_failure(
|
||||
base_branch,
|
||||
f"`git fetch origin {base_branch}` failed",
|
||||
e.stderr or "",
|
||||
)
|
||||
sys.exit(3)
|
||||
|
||||
try:
|
||||
result = subprocess.run(
|
||||
["git", "rev-list", "--count", f"HEAD..origin/{base_branch}"],
|
||||
check=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
cwd=cwd,
|
||||
)
|
||||
behind = int(result.stdout.strip())
|
||||
except subprocess.CalledProcessError as e:
|
||||
_print_freshness_failure(
|
||||
base_branch,
|
||||
f"`git rev-list HEAD..origin/{base_branch}` failed",
|
||||
e.stderr or "",
|
||||
)
|
||||
sys.exit(3)
|
||||
except ValueError:
|
||||
_print_freshness_failure(
|
||||
base_branch,
|
||||
"could not parse commit count from `git rev-list`",
|
||||
)
|
||||
sys.exit(3)
|
||||
|
||||
if behind > 0:
|
||||
_print_stale_branch_refusal(base_branch, behind)
|
||||
sys.exit(3)
|
||||
|
||||
print(f"Branch freshness OK: up to date with origin/{base_branch}.")
|
||||
|
||||
|
||||
def _print_destructive_refusal(destructive_lines: list) -> None:
|
||||
"""Loudly refuse to write a destructive migration and explain how to proceed."""
|
||||
banner = "=" * 72
|
||||
out = sys.stderr
|
||||
print(banner, file=out)
|
||||
print(
|
||||
" DESTRUCTIVE MIGRATION DETECTED — REFUSING TO WRITE MIGRATION FILE", file=out
|
||||
)
|
||||
print(banner, file=out)
|
||||
print("", file=out)
|
||||
print(
|
||||
"The generated migration contains the following destructive statements:",
|
||||
file=out,
|
||||
)
|
||||
print("", file=out)
|
||||
for line in destructive_lines:
|
||||
print(f" {line}", file=out)
|
||||
print("", file=out)
|
||||
print(
|
||||
"This very often means your branch is OUT OF DATE, or your local\n"
|
||||
"schema.prisma is inconsistent with the migrations/ directory. A\n"
|
||||
"previous incident saw newly-added columns silently dropped this way\n"
|
||||
"and merged to main. Stop and verify before proceeding.",
|
||||
file=out,
|
||||
)
|
||||
print("", file=out)
|
||||
print("Before re-running:", file=out)
|
||||
print(
|
||||
" 1. git fetch origin && git status # confirm branch is up to date", file=out
|
||||
)
|
||||
print(
|
||||
" 2. Re-check all schema.prisma files are in sync (runbook Step 0)", file=out
|
||||
)
|
||||
print(" 3. Review EACH DROP above — is it actually intended?", file=out)
|
||||
print(" 4. If (and only if) the drops are intentional, re-run with:", file=out)
|
||||
print(" --allow-destructive", file=out)
|
||||
print("", file=out)
|
||||
print(banner, file=out)
|
||||
print(
|
||||
" AI AGENTS / ASSISTANTS: DO NOT automatically re-run this command\n"
|
||||
" with --allow-destructive. Surface this error to the human operator\n"
|
||||
" and wait for their explicit confirmation before passing the flag.\n"
|
||||
" Passing the flag without human review is the exact failure mode\n"
|
||||
" this guard exists to prevent.",
|
||||
file=out,
|
||||
)
|
||||
print(banner, file=out)
|
||||
|
||||
|
||||
def create_migration(
|
||||
migration_name: str = None,
|
||||
allow_destructive: bool = False,
|
||||
base_branch: str = DEFAULT_BASE_BRANCH,
|
||||
skip_freshness_check: bool = False,
|
||||
):
|
||||
"""
|
||||
Create a new migration SQL file in the migrations directory by comparing
|
||||
current database state with schema
|
||||
current database state with schema.
|
||||
|
||||
Args:
|
||||
migration_name (str): Name for the migration
|
||||
allow_destructive (bool): Required to write a migration that contains
|
||||
DROP COLUMN, DROP TABLE, or DROP INDEX statements. Without this
|
||||
flag, the script exits non-zero and prints guidance.
|
||||
base_branch (str): Branch to check freshness against
|
||||
(default: "litellm_internal_staging").
|
||||
skip_freshness_check (bool): Skip the "branch is up to date" check.
|
||||
Only for intentional migrations against an older base.
|
||||
"""
|
||||
root_dir = Path(__file__).parent.parent
|
||||
|
||||
if skip_freshness_check:
|
||||
print(
|
||||
"WARNING: freshness check skipped (--skip-freshness-check). "
|
||||
"Generating a migration from a stale branch can silently drop columns."
|
||||
)
|
||||
else:
|
||||
_check_branch_freshness(root_dir, base_branch)
|
||||
|
||||
try:
|
||||
# Get paths
|
||||
root_dir = Path(__file__).parent.parent
|
||||
migrations_dir = root_dir / "litellm-proxy-extras" / "litellm_proxy_extras" / "migrations"
|
||||
migrations_dir = (
|
||||
root_dir / "litellm-proxy-extras" / "litellm_proxy_extras" / "migrations"
|
||||
)
|
||||
schema_path = root_dir / "schema.prisma"
|
||||
|
||||
# Create temporary PostgreSQL database
|
||||
|
|
@ -57,7 +268,27 @@ def create_migration(migration_name: str = None):
|
|||
check=True,
|
||||
)
|
||||
|
||||
if result.stdout.strip():
|
||||
# Prisma emits the literal "-- This is an empty migration." when
|
||||
# there's no real drift. Treat that as "no changes".
|
||||
diff_sql = result.stdout
|
||||
stripped = diff_sql.strip()
|
||||
is_empty_diff = (
|
||||
not stripped or stripped == "-- This is an empty migration."
|
||||
)
|
||||
|
||||
if not is_empty_diff:
|
||||
destructive_lines = _find_destructive_statements(diff_sql)
|
||||
if destructive_lines and not allow_destructive:
|
||||
_print_destructive_refusal(destructive_lines)
|
||||
sys.exit(2)
|
||||
if destructive_lines and allow_destructive:
|
||||
print(
|
||||
"WARNING: writing destructive migration "
|
||||
"(--allow-destructive passed). Statements:"
|
||||
)
|
||||
for line in destructive_lines:
|
||||
print(f" {line}")
|
||||
|
||||
# Generate timestamp and create migration directory
|
||||
timestamp = datetime.now().strftime("%Y%m%d%H%M%S")
|
||||
migration_name = migration_name or "unnamed_migration"
|
||||
|
|
@ -66,7 +297,7 @@ def create_migration(migration_name: str = None):
|
|||
|
||||
# Write the SQL to migration.sql
|
||||
migration_file = migration_dir / "migration.sql"
|
||||
migration_file.write_text(result.stdout)
|
||||
migration_file.write_text(diff_sql)
|
||||
|
||||
print(f"Created migration in {migration_dir}")
|
||||
return True
|
||||
|
|
@ -88,8 +319,48 @@ def create_migration(migration_name: str = None):
|
|||
|
||||
|
||||
if __name__ == "__main__":
|
||||
# If running directly, can optionally pass migration name as argument
|
||||
import sys
|
||||
|
||||
migration_name = sys.argv[1] if len(sys.argv) > 1 else None
|
||||
create_migration(migration_name)
|
||||
parser = argparse.ArgumentParser(
|
||||
description=(
|
||||
"Generate a Prisma migration by diffing the temp DB "
|
||||
"(existing migrations applied) against schema.prisma."
|
||||
)
|
||||
)
|
||||
parser.add_argument(
|
||||
"migration_name",
|
||||
nargs="?",
|
||||
default=None,
|
||||
help="Name for the migration (used in the generated directory name).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--allow-destructive",
|
||||
action="store_true",
|
||||
help=(
|
||||
"Required to write a migration that contains DROP COLUMN, "
|
||||
"DROP TABLE, or DROP INDEX. Without this flag, destructive "
|
||||
"diffs are refused."
|
||||
),
|
||||
)
|
||||
parser.add_argument(
|
||||
"--base-branch",
|
||||
default=DEFAULT_BASE_BRANCH,
|
||||
help=(
|
||||
f"Branch to check freshness against (default: {DEFAULT_BASE_BRANCH}). "
|
||||
"The script fetches origin/<base-branch> and refuses to run if HEAD "
|
||||
"is behind it."
|
||||
),
|
||||
)
|
||||
parser.add_argument(
|
||||
"--skip-freshness-check",
|
||||
action="store_true",
|
||||
help=(
|
||||
"Bypass the 'branch is up to date' check. Only for intentional "
|
||||
"migrations against an older base. Pairs poorly with automation."
|
||||
),
|
||||
)
|
||||
args = parser.parse_args()
|
||||
create_migration(
|
||||
args.migration_name,
|
||||
allow_destructive=args.allow_destructive,
|
||||
base_branch=args.base_branch,
|
||||
skip_freshness_check=args.skip_freshness_check,
|
||||
)
|
||||
|
|
|
|||
|
|
@ -17,6 +17,9 @@ component_management:
|
|||
- component_id: "Proxy_Authentication"
|
||||
paths:
|
||||
- "*/proxy/auth/**"
|
||||
- component_id: "Enterprise"
|
||||
paths:
|
||||
- "enterprise/**"
|
||||
comment:
|
||||
layout: "header, diff, flags, components" # show component info in the PR comment
|
||||
|
||||
|
|
|
|||
|
|
@ -230,7 +230,7 @@ model_list:
|
|||
# AWS Bedrock
|
||||
- model_name: claude-bedrock
|
||||
litellm_params:
|
||||
model: bedrock/anthropic.claude-3-5-sonnet-20241022-v2:0
|
||||
model: bedrock/us.anthropic.claude-haiku-4-5-20251001-v1:0
|
||||
aws_access_key_id: os.environ/AWS_ACCESS_KEY_ID
|
||||
aws_secret_access_key: os.environ/AWS_SECRET_ACCESS_KEY
|
||||
aws_region_name: us-east-1
|
||||
|
|
|
|||
|
|
@ -24,24 +24,26 @@ async def interactive_chat_with_mcp():
|
|||
Interactive CLI chat with the agent and MCP server
|
||||
"""
|
||||
config = Config()
|
||||
|
||||
|
||||
# Configure Anthropic SDK to point to LiteLLM gateway
|
||||
litellm_base_url = setup_litellm_env(config)
|
||||
|
||||
|
||||
# Fetch available models from proxy
|
||||
available_models = await fetch_available_models(litellm_base_url, config.LITELLM_API_KEY)
|
||||
|
||||
available_models = await fetch_available_models(
|
||||
litellm_base_url, config.LITELLM_API_KEY
|
||||
)
|
||||
|
||||
current_model = config.LITELLM_MODEL
|
||||
|
||||
|
||||
# MCP server configuration
|
||||
mcp_server_url = f"{litellm_base_url}/mcp/deepwiki2"
|
||||
use_mcp = os.getenv("USE_MCP", "true").lower() == "true"
|
||||
|
||||
|
||||
if not use_mcp:
|
||||
print("⚠️ MCP disabled via USE_MCP=false")
|
||||
|
||||
|
||||
print_header(litellm_base_url, current_model, has_mcp=use_mcp)
|
||||
|
||||
|
||||
while True:
|
||||
# Configure agent options
|
||||
if use_mcp:
|
||||
|
|
@ -58,7 +60,7 @@ async def interactive_chat_with_mcp():
|
|||
"url": mcp_server_url,
|
||||
"headers": {
|
||||
"Authorization": f"Bearer {config.LITELLM_API_KEY}"
|
||||
}
|
||||
},
|
||||
}
|
||||
},
|
||||
)
|
||||
|
|
@ -78,12 +80,12 @@ async def interactive_chat_with_mcp():
|
|||
model=current_model,
|
||||
max_turns=50,
|
||||
)
|
||||
|
||||
|
||||
# Create agent client
|
||||
try:
|
||||
async with ClaudeSDKClient(options=options) as client:
|
||||
conversation_active = True
|
||||
|
||||
|
||||
while conversation_active:
|
||||
# Get user input
|
||||
try:
|
||||
|
|
@ -91,34 +93,36 @@ async def interactive_chat_with_mcp():
|
|||
except (EOFError, KeyboardInterrupt):
|
||||
print("\n\n👋 Goodbye!")
|
||||
return
|
||||
|
||||
|
||||
# Handle commands
|
||||
if user_input.lower() in ['quit', 'exit']:
|
||||
if user_input.lower() in ["quit", "exit"]:
|
||||
print("\n👋 Goodbye!")
|
||||
return
|
||||
|
||||
if user_input.lower() == 'clear':
|
||||
|
||||
if user_input.lower() == "clear":
|
||||
print("\n🔄 Starting new conversation...\n")
|
||||
conversation_active = False
|
||||
continue
|
||||
|
||||
if user_input.lower() == 'models':
|
||||
|
||||
if user_input.lower() == "models":
|
||||
handle_model_list(available_models, current_model)
|
||||
continue
|
||||
|
||||
if user_input.lower() == 'model':
|
||||
new_model, should_restart = handle_model_switch(available_models, current_model)
|
||||
|
||||
if user_input.lower() == "model":
|
||||
new_model, should_restart = handle_model_switch(
|
||||
available_models, current_model
|
||||
)
|
||||
if should_restart:
|
||||
current_model = new_model
|
||||
conversation_active = False
|
||||
continue
|
||||
|
||||
|
||||
if not user_input:
|
||||
continue
|
||||
|
||||
|
||||
# Stream response from agent
|
||||
await stream_response(client, user_input)
|
||||
|
||||
|
||||
except Exception as e:
|
||||
print(f"\n❌ Error creating agent client: {e}")
|
||||
print("This might be an MCP configuration issue. Try running without MCP:")
|
||||
|
|
|
|||
|
|
@ -8,13 +8,13 @@ import httpx
|
|||
|
||||
class Config:
|
||||
"""Configuration for LiteLLM Gateway connection"""
|
||||
|
||||
|
||||
# LiteLLM proxy URL (default to local instance)
|
||||
LITELLM_PROXY_URL = os.getenv("LITELLM_PROXY_URL", "http://localhost:4000")
|
||||
|
||||
|
||||
# LiteLLM API key (master key or virtual key)
|
||||
LITELLM_API_KEY = os.getenv("LITELLM_API_KEY", "sk-1234")
|
||||
|
||||
|
||||
# Model name as configured in LiteLLM (e.g., "bedrock-claude-sonnet-4", "gpt-4", etc.)
|
||||
LITELLM_MODEL = os.getenv("LITELLM_MODEL", "bedrock-claude-sonnet-4.5")
|
||||
|
||||
|
|
@ -28,7 +28,7 @@ async def fetch_available_models(base_url: str, api_key: str) -> list[str]:
|
|||
response = await client.get(
|
||||
f"{base_url}/models",
|
||||
headers={"Authorization": f"Bearer {api_key}"},
|
||||
timeout=10.0
|
||||
timeout=10.0,
|
||||
)
|
||||
response.raise_for_status()
|
||||
data = response.json()
|
||||
|
|
@ -50,7 +50,7 @@ def setup_litellm_env(config: Config):
|
|||
"""
|
||||
Configure environment variables to point Agent SDK to LiteLLM
|
||||
"""
|
||||
litellm_base_url = config.LITELLM_PROXY_URL.rstrip('/')
|
||||
litellm_base_url = config.LITELLM_PROXY_URL.rstrip("/")
|
||||
os.environ["ANTHROPIC_BASE_URL"] = litellm_base_url
|
||||
os.environ["ANTHROPIC_API_KEY"] = config.LITELLM_API_KEY
|
||||
return litellm_base_url
|
||||
|
|
@ -87,10 +87,12 @@ def handle_model_list(available_models: list[str], current_model: str):
|
|||
print(f" {marker} {i}. {model}")
|
||||
|
||||
|
||||
def handle_model_switch(available_models: list[str], current_model: str) -> tuple[str, bool]:
|
||||
def handle_model_switch(
|
||||
available_models: list[str], current_model: str
|
||||
) -> tuple[str, bool]:
|
||||
"""
|
||||
Handle model switching
|
||||
|
||||
|
||||
Returns:
|
||||
tuple: (new_model, should_restart_conversation)
|
||||
"""
|
||||
|
|
@ -98,7 +100,7 @@ def handle_model_switch(available_models: list[str], current_model: str) -> tupl
|
|||
for i, model in enumerate(available_models, 1):
|
||||
marker = "✓" if model == current_model else " "
|
||||
print(f" {marker} {i}. {model}")
|
||||
|
||||
|
||||
try:
|
||||
choice = input("\nEnter number (or press Enter to cancel): ").strip()
|
||||
if choice:
|
||||
|
|
@ -112,7 +114,7 @@ def handle_model_switch(available_models: list[str], current_model: str) -> tupl
|
|||
print("❌ Invalid choice")
|
||||
except (ValueError, IndexError):
|
||||
print("❌ Invalid input")
|
||||
|
||||
|
||||
return current_model, False
|
||||
|
||||
|
||||
|
|
@ -120,41 +122,43 @@ async def stream_response(client, user_input: str):
|
|||
"""
|
||||
Stream response from the agent
|
||||
"""
|
||||
print("\n🤖 Assistant: ", end='', flush=True)
|
||||
|
||||
print("\n🤖 Assistant: ", end="", flush=True)
|
||||
|
||||
try:
|
||||
await client.query(user_input)
|
||||
|
||||
|
||||
# Show loading indicator
|
||||
print("⏳ thinking...", end='', flush=True)
|
||||
|
||||
print("⏳ thinking...", end="", flush=True)
|
||||
|
||||
# Stream the response
|
||||
first_chunk = True
|
||||
async for msg in client.receive_response():
|
||||
# Clear loading indicator on first message
|
||||
if first_chunk:
|
||||
print("\r🤖 Assistant: ", end='', flush=True)
|
||||
print("\r🤖 Assistant: ", end="", flush=True)
|
||||
first_chunk = False
|
||||
|
||||
|
||||
# Handle different message types
|
||||
if hasattr(msg, 'type'):
|
||||
if msg.type == 'content_block_delta':
|
||||
if hasattr(msg, "type"):
|
||||
if msg.type == "content_block_delta":
|
||||
# Streaming text delta
|
||||
if hasattr(msg, 'delta') and hasattr(msg.delta, 'text'):
|
||||
print(msg.delta.text, end='', flush=True)
|
||||
elif msg.type == 'content_block_start':
|
||||
if hasattr(msg, "delta") and hasattr(msg.delta, "text"):
|
||||
print(msg.delta.text, end="", flush=True)
|
||||
elif msg.type == "content_block_start":
|
||||
# Start of content block
|
||||
if hasattr(msg, 'content_block') and hasattr(msg.content_block, 'text'):
|
||||
print(msg.content_block.text, end='', flush=True)
|
||||
|
||||
if hasattr(msg, "content_block") and hasattr(
|
||||
msg.content_block, "text"
|
||||
):
|
||||
print(msg.content_block.text, end="", flush=True)
|
||||
|
||||
# Fallback to original content handling
|
||||
if hasattr(msg, 'content'):
|
||||
if hasattr(msg, "content"):
|
||||
for content_block in msg.content:
|
||||
if hasattr(content_block, 'text'):
|
||||
print(content_block.text, end='', flush=True)
|
||||
|
||||
if hasattr(content_block, "text"):
|
||||
print(content_block.text, end="", flush=True)
|
||||
|
||||
print() # New line after response
|
||||
|
||||
|
||||
except Exception as e:
|
||||
print(f"\r\n❌ Error: {e}")
|
||||
print("Please check your LiteLLM gateway is running and configured correctly.")
|
||||
|
|
|
|||
|
|
@ -24,17 +24,19 @@ async def interactive_chat():
|
|||
Interactive CLI chat with the agent
|
||||
"""
|
||||
config = Config()
|
||||
|
||||
|
||||
# Configure Anthropic SDK to point to LiteLLM gateway
|
||||
litellm_base_url = setup_litellm_env(config)
|
||||
|
||||
|
||||
# Fetch available models from proxy
|
||||
available_models = await fetch_available_models(litellm_base_url, config.LITELLM_API_KEY)
|
||||
|
||||
available_models = await fetch_available_models(
|
||||
litellm_base_url, config.LITELLM_API_KEY
|
||||
)
|
||||
|
||||
current_model = config.LITELLM_MODEL
|
||||
|
||||
|
||||
print_header(litellm_base_url, current_model)
|
||||
|
||||
|
||||
while True:
|
||||
# Configure agent options for each conversation
|
||||
options = ClaudeAgentOptions(
|
||||
|
|
@ -42,11 +44,11 @@ async def interactive_chat():
|
|||
model=current_model,
|
||||
max_turns=50,
|
||||
)
|
||||
|
||||
|
||||
# Create agent client
|
||||
async with ClaudeSDKClient(options=options) as client:
|
||||
conversation_active = True
|
||||
|
||||
|
||||
while conversation_active:
|
||||
# Get user input
|
||||
try:
|
||||
|
|
@ -54,31 +56,33 @@ async def interactive_chat():
|
|||
except (EOFError, KeyboardInterrupt):
|
||||
print("\n\n👋 Goodbye!")
|
||||
return
|
||||
|
||||
|
||||
# Handle commands
|
||||
if user_input.lower() in ['quit', 'exit']:
|
||||
if user_input.lower() in ["quit", "exit"]:
|
||||
print("\n👋 Goodbye!")
|
||||
return
|
||||
|
||||
if user_input.lower() == 'clear':
|
||||
|
||||
if user_input.lower() == "clear":
|
||||
print("\n🔄 Starting new conversation...\n")
|
||||
conversation_active = False
|
||||
continue
|
||||
|
||||
if user_input.lower() == 'models':
|
||||
|
||||
if user_input.lower() == "models":
|
||||
handle_model_list(available_models, current_model)
|
||||
continue
|
||||
|
||||
if user_input.lower() == 'model':
|
||||
new_model, should_restart = handle_model_switch(available_models, current_model)
|
||||
|
||||
if user_input.lower() == "model":
|
||||
new_model, should_restart = handle_model_switch(
|
||||
available_models, current_model
|
||||
)
|
||||
if should_restart:
|
||||
current_model = new_model
|
||||
conversation_active = False
|
||||
continue
|
||||
|
||||
|
||||
if not user_input:
|
||||
continue
|
||||
|
||||
|
||||
# Stream response from agent
|
||||
await stream_response(client, user_input)
|
||||
|
||||
|
|
|
|||
|
|
@ -178,4 +178,4 @@ Benchmark Results for 'When will BerriAI IPO?':
|
|||
```
|
||||
|
||||
## Support
|
||||
**🤝 Schedule a 1-on-1 Session:** Book a [1-on-1 session](https://calendly.com/d/cx9p-5yf-2nm/litellm-introductions) with Krrish and Ishaan, the founders, to discuss any issues, provide feedback, or explore how we can improve LiteLLM for you.
|
||||
**🤝 Schedule a 1-on-1 Session:** Book a [1-on-1 session](https://enterprise.litellm.ai/demo) with Krrish and Ishaan, the founders, to discuss any issues, provide feedback, or explore how we can improve LiteLLM for you.
|
||||
|
|
|
|||
|
|
@ -143,7 +143,6 @@ All responses from the server are returned in the following format (for all LLM
|
|||
|
||||
- [Our calendar 👋](https://calendly.com/d/4mp-gd3-k5k/berriai-1-1-onboarding-litellm-hosted-version)
|
||||
- [Community Discord 💭](https://discord.gg/wuPM9dRgDw)
|
||||
- Our numbers 📞 +1 (770) 8783-106 / +1 (412) 618-6238
|
||||
- Our emails ✉️ ishaan@berri.ai / krrish@berri.ai
|
||||
|
||||
## Roadmap
|
||||
|
|
|
|||
|
|
@ -1 +1 @@
|
|||
litellm==1.61.15
|
||||
litellm==1.83.5
|
||||
|
|
@ -11,15 +11,15 @@ BEDROCK_BATCH_MODEL = "bedrock/batch-anthropic.claude-3-5-sonnet-20240620-v1:0"
|
|||
batch_input_file = client.files.create(
|
||||
file=open("./bedrock_batch_completions.jsonl", "rb"),
|
||||
purpose="batch",
|
||||
extra_body={"target_model_names": BEDROCK_BATCH_MODEL}
|
||||
extra_body={"target_model_names": BEDROCK_BATCH_MODEL},
|
||||
)
|
||||
print(batch_input_file)
|
||||
|
||||
# Create batch
|
||||
batch = client.batches.create(
|
||||
batch = client.batches.create(
|
||||
input_file_id=batch_input_file.id,
|
||||
endpoint="/v1/chat/completions",
|
||||
completion_window="24h",
|
||||
metadata={"description": "Test batch job"},
|
||||
)
|
||||
print(batch)
|
||||
print(batch)
|
||||
|
|
|
|||
|
|
@ -8,6 +8,7 @@ in your Python scripts after running `litellm-proxy login`.
|
|||
|
||||
from textwrap import indent
|
||||
import litellm
|
||||
|
||||
LITELLM_BASE_URL = "http://localhost:4000/"
|
||||
|
||||
|
||||
|
|
@ -15,38 +16,38 @@ def main():
|
|||
"""Using CLI token with LiteLLM SDK"""
|
||||
print("🚀 Using CLI Token with LiteLLM SDK")
|
||||
print("=" * 40)
|
||||
#litellm._turn_on_debug()
|
||||
|
||||
# litellm._turn_on_debug()
|
||||
|
||||
# Get the CLI token
|
||||
api_key = litellm.get_litellm_gateway_api_key()
|
||||
|
||||
|
||||
if not api_key:
|
||||
print("❌ No CLI token found. Please run 'litellm-proxy login' first.")
|
||||
return
|
||||
|
||||
|
||||
print("✅ Found CLI token.")
|
||||
|
||||
available_models = litellm.get_valid_models(
|
||||
check_provider_endpoint=True,
|
||||
custom_llm_provider="litellm_proxy",
|
||||
api_key=api_key,
|
||||
api_base=LITELLM_BASE_URL
|
||||
api_base=LITELLM_BASE_URL,
|
||||
)
|
||||
|
||||
|
||||
print("✅ Available models:")
|
||||
if available_models:
|
||||
for i, model in enumerate(available_models, 1):
|
||||
print(f" {i:2d}. {model}")
|
||||
else:
|
||||
print(" No models available")
|
||||
|
||||
|
||||
# Use with LiteLLM
|
||||
try:
|
||||
response = litellm.completion(
|
||||
model="litellm_proxy/gemini/gemini-2.5-flash",
|
||||
messages=[{"role": "user", "content": "Hello from CLI token!"}],
|
||||
api_key=api_key,
|
||||
base_url=LITELLM_BASE_URL
|
||||
base_url=LITELLM_BASE_URL,
|
||||
)
|
||||
print(f"✅ LLM Response: {response.model_dump_json(indent=4)}")
|
||||
except Exception as e:
|
||||
|
|
@ -55,7 +56,7 @@ def main():
|
|||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
|
||||
|
||||
print("\n💡 Tips:")
|
||||
print("1. Run 'litellm-proxy login' to authenticate first")
|
||||
print("2. Replace 'https://your-proxy.com' with your actual proxy URL")
|
||||
|
|
|
|||
|
|
@ -3,11 +3,12 @@ Use LiteLLM Proxy MCP Gateway to call MCP tools.
|
|||
|
||||
When using LiteLLM Proxy, you can use the same MCP tools across all your LLM providers.
|
||||
"""
|
||||
|
||||
import openai
|
||||
|
||||
client = openai.OpenAI(
|
||||
api_key="sk-1234", # paste your litellm proxy api key here
|
||||
base_url="http://localhost:4000" # paste your litellm proxy base url here
|
||||
api_key="sk-1234", # paste your litellm proxy api key here
|
||||
base_url="http://localhost:4000", # paste your litellm proxy base url here
|
||||
)
|
||||
print("Making API request to Responses API with MCP tools")
|
||||
|
||||
|
|
@ -17,7 +18,7 @@ response = client.responses.create(
|
|||
{
|
||||
"role": "user",
|
||||
"content": "give me TLDR of what BerriAI/litellm repo is about",
|
||||
"type": "message"
|
||||
"type": "message",
|
||||
}
|
||||
],
|
||||
tools=[
|
||||
|
|
@ -25,11 +26,11 @@ response = client.responses.create(
|
|||
"type": "mcp",
|
||||
"server_label": "litellm",
|
||||
"server_url": "litellm_proxy",
|
||||
"require_approval": "never"
|
||||
"require_approval": "never",
|
||||
}
|
||||
],
|
||||
stream=True,
|
||||
tool_choice="required"
|
||||
tool_choice="required",
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
|
|
|
|||
|
|
@ -164,7 +164,6 @@ All responses from the server are returned in the following format (for all LLM
|
|||
|
||||
- [Our calendar 👋](https://calendly.com/d/4mp-gd3-k5k/berriai-1-1-onboarding-litellm-hosted-version)
|
||||
- [Community Discord 💭](https://discord.gg/wuPM9dRgDw)
|
||||
- Our numbers 📞 +1 (770) 8783-106 / +1 (412) 618-6238
|
||||
- Our emails ✉️ ishaan@berri.ai / krrish@berri.ai
|
||||
|
||||
## Roadmap
|
||||
|
|
|
|||
|
|
@ -40,8 +40,10 @@ class InMemorySecretManager(CustomSecretManager):
|
|||
) -> Optional[str]:
|
||||
"""Read secret synchronously"""
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
|
||||
verbose_proxy_logger.info(f"CUSTOM SECRET MANAGER: LOOKING FOR SECRET: {secret_name}")
|
||||
|
||||
verbose_proxy_logger.info(
|
||||
f"CUSTOM SECRET MANAGER: LOOKING FOR SECRET: {secret_name}"
|
||||
)
|
||||
value = self.secrets.get(secret_name)
|
||||
verbose_proxy_logger.info(f"CUSTOM SECRET MANAGER: READ SECRET: {value}")
|
||||
return value
|
||||
|
|
@ -76,4 +78,3 @@ class InMemorySecretManager(CustomSecretManager):
|
|||
del self.secrets[secret_name]
|
||||
return {"status": "deleted", "secret_name": secret_name}
|
||||
return {"status": "not_found", "secret_name": secret_name}
|
||||
|
||||
|
|
|
|||
|
|
@ -5,6 +5,7 @@ This example shows how to use LiveKit's xAI realtime plugin through LiteLLM prox
|
|||
LiteLLM acts as a unified interface, allowing you to switch between xAI, OpenAI,
|
||||
and Azure realtime APIs without changing your agent code.
|
||||
"""
|
||||
|
||||
import asyncio
|
||||
import json
|
||||
import os
|
||||
|
|
@ -23,71 +24,79 @@ async def run_voice_agent():
|
|||
2. Sends a user message
|
||||
3. Streams back the response
|
||||
"""
|
||||
|
||||
|
||||
url = f"ws://{PROXY_URL.replace('http://', '').replace('https://', '')}/v1/realtime?model={MODEL}"
|
||||
headers = {"Authorization": f"Bearer {API_KEY}"}
|
||||
|
||||
|
||||
print(f"🎙️ Connecting to voice agent...")
|
||||
print(f" Model: {MODEL}")
|
||||
print(f" Proxy: {PROXY_URL}")
|
||||
print()
|
||||
|
||||
|
||||
async with websockets.connect(url, additional_headers=headers) as ws:
|
||||
# Receive initial connection event
|
||||
initial = json.loads(await ws.recv())
|
||||
print(f"✅ Connected! Event: {initial['type']}\n")
|
||||
|
||||
|
||||
# Get user input
|
||||
user_message = input("💬 Your message: ").strip()
|
||||
if not user_message:
|
||||
user_message = "Tell me a fun fact about AI!"
|
||||
|
||||
|
||||
print(f"\n🤖 Sending to {MODEL}...\n")
|
||||
|
||||
|
||||
# Send user message
|
||||
await ws.send(json.dumps({
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{"type": "input_text", "text": user_message}]
|
||||
}
|
||||
}))
|
||||
|
||||
await ws.send(
|
||||
json.dumps(
|
||||
{
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{"type": "input_text", "text": user_message}],
|
||||
},
|
||||
}
|
||||
)
|
||||
)
|
||||
|
||||
# Request response
|
||||
await ws.send(json.dumps({
|
||||
"type": "response.create",
|
||||
"response": {"modalities": ["text", "audio"]}
|
||||
}))
|
||||
|
||||
await ws.send(
|
||||
json.dumps(
|
||||
{
|
||||
"type": "response.create",
|
||||
"response": {"modalities": ["text", "audio"]},
|
||||
}
|
||||
)
|
||||
)
|
||||
|
||||
# Stream response
|
||||
print("🎤 Response: ", end='', flush=True)
|
||||
print("🎤 Response: ", end="", flush=True)
|
||||
transcript = []
|
||||
|
||||
|
||||
try:
|
||||
while True:
|
||||
msg = await asyncio.wait_for(ws.recv(), timeout=15.0)
|
||||
event = json.loads(msg)
|
||||
|
||||
|
||||
# Capture transcript deltas
|
||||
if event['type'] == 'response.output_audio_transcript.delta':
|
||||
delta = event.get('delta', '')
|
||||
if event["type"] == "response.output_audio_transcript.delta":
|
||||
delta = event.get("delta", "")
|
||||
if delta:
|
||||
print(delta, end='', flush=True)
|
||||
print(delta, end="", flush=True)
|
||||
transcript.append(delta)
|
||||
|
||||
|
||||
# Done when response completes
|
||||
elif event['type'] == 'response.done':
|
||||
elif event["type"] == "response.done":
|
||||
break
|
||||
|
||||
|
||||
except asyncio.TimeoutError:
|
||||
pass
|
||||
|
||||
|
||||
print("\n")
|
||||
|
||||
|
||||
if transcript:
|
||||
print(f"✅ Complete response: {''.join(transcript)}")
|
||||
|
||||
|
||||
await ws.close()
|
||||
|
||||
|
||||
|
|
@ -97,7 +106,7 @@ def main():
|
|||
print("LiveKit xAI Voice Agent via LiteLLM Proxy")
|
||||
print("=" * 70)
|
||||
print()
|
||||
|
||||
|
||||
try:
|
||||
asyncio.run(run_voice_agent())
|
||||
except KeyboardInterrupt:
|
||||
|
|
|
|||
|
|
@ -9,6 +9,32 @@ This document provides comprehensive instructions for AI agents to generate rele
|
|||
3. **Previous Version Commit Hash** - To compare model pricing changes
|
||||
4. **Reference Release Notes** - Use recent stable releases (v1.76.3-stable, v1.77.2-stable) as templates for consistent formatting
|
||||
|
||||
### Resolving Staging PRs
|
||||
|
||||
The GitHub release page (e.g. `https://github.com/BerriAI/litellm/releases/tag/v1.83.3-stable`) does **not** list the real changelog directly. The "What's Changed" section contains **staging PRs** that each bundle many individual commits/PRs. For example:
|
||||
|
||||
- `Litellm oss staging 03 14 2026 by @RheagalFire in #23686`
|
||||
- `Litellm ryan march 16 by @ryan-crabbe in #23822`
|
||||
|
||||
To get the real changelog, you MUST click into each staging PR (e.g. `#23686`, `#23822`), open its **Commits** tab, and extract every underlying commit/PR (look for the `(#NNNNN)` suffix on commit titles). Those underlying PRs — not the staging PRs — are what get categorized in the release notes. Never treat a staging PR title as a single changelog entry.
|
||||
|
||||
**IMPORTANT — staging PRs are not the complete source.** Some PRs land on the release branch *before* the staging PRs and are therefore not reachable via `gh api /pulls/<staging>/commits`. GitHub's auto-generated "What's Changed" on the release page also misses these. To catch every PR in the release, you MUST additionally walk the full git log range between the previous release's commit and this release's commit:
|
||||
|
||||
```bash
|
||||
git fetch origin --tags
|
||||
git log <prev_release_commit>..<this_release_commit> --oneline | grep -oE '#[0-9]+' | sort -u
|
||||
```
|
||||
|
||||
Union the PR set from the staging-PR walk with the PR set from `git log`. Any PR in `git log` but missing from your staging-expanded set is almost certainly a content PR that merged directly to the release branch — fetch its title/body with `gh pr view <N>` and categorize it. Do not trust the GH release body or the staging PRs alone as the authoritative list.
|
||||
|
||||
**Sanity check for new contributors.** The GH release body's "New Contributors" list is a *floor*, not authoritative. For every PR author who appears in the release (including underlying PRs from staging and PRs found only via `git log`), verify whether they are a first-time contributor by running:
|
||||
|
||||
```bash
|
||||
gh api "search/issues?q=is:pr+author:<login>+repo:BerriAI/litellm+is:merged&sort=created&order=asc" --jq '.items[0] | {n:.number, merged:.closed_at}'
|
||||
```
|
||||
|
||||
If the author's earliest merged PR number matches a PR in this release window, they are a new contributor. If their earliest merged PR predates the previous release tag, they are not. Do not copy the GH release body's list blindly — it can both miss contributors (PRs that merged via an older dev branch) and falsely include contributors whose "first" PR in this window was not actually their first ever.
|
||||
|
||||
## Step-by-Step Process
|
||||
|
||||
### 1. Initial Setup and Analysis
|
||||
|
|
|
|||
|
|
@ -1,10 +1,9 @@
|
|||
import base64
|
||||
from openai import OpenAI
|
||||
import time
|
||||
client = OpenAI(
|
||||
base_url="http://0.0.0.0:4001",
|
||||
api_key="sk-1234"
|
||||
)
|
||||
|
||||
client = OpenAI(base_url="http://0.0.0.0:4001", api_key="sk-1234")
|
||||
|
||||
|
||||
# Function to encode the image
|
||||
def encode_image(image_path):
|
||||
|
|
@ -20,12 +19,12 @@ base64_image = encode_image(image_path)
|
|||
|
||||
|
||||
response = client.responses.create(
|
||||
model="bedrock/us.anthropic.claude-3-5-sonnet-20241022-v2:0",
|
||||
model="bedrock/us.anthropic.claude-haiku-4-5-20251001-v1:0",
|
||||
input=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{ "type": "input_text", "text": "what color is the image"},
|
||||
{"type": "input_text", "text": "what color is the image"},
|
||||
{
|
||||
"type": "input_image",
|
||||
"image_url": f"data:image/jpeg;base64,{base64_image}",
|
||||
|
|
@ -36,18 +35,15 @@ response = client.responses.create(
|
|||
)
|
||||
|
||||
|
||||
|
||||
print(response.output_text)
|
||||
print("response1 id===", response.id)
|
||||
print("sleeping for 20 seconds...")
|
||||
time.sleep(20)
|
||||
print("making follow up request for existing id")
|
||||
response2 = client.responses.create(
|
||||
model="bedrock/us.anthropic.claude-3-5-sonnet-20241022-v2:0",
|
||||
model="bedrock/us.anthropic.claude-haiku-4-5-20251001-v1:0",
|
||||
previous_response_id=response.id,
|
||||
input="ok, and what objects are in the image?"
|
||||
input="ok, and what objects are in the image?",
|
||||
)
|
||||
|
||||
print(response2.output_text)
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -52,11 +52,11 @@ class RealtimeClient:
|
|||
async def connect(self):
|
||||
"""Connect to LiteLLM proxy realtime endpoint."""
|
||||
print(f"Connecting to {self.url}...")
|
||||
|
||||
|
||||
headers = {}
|
||||
if self.api_key:
|
||||
headers["Authorization"] = f"Bearer {self.api_key}"
|
||||
|
||||
|
||||
self.ws = await websockets.connect(
|
||||
self.url,
|
||||
additional_headers=headers,
|
||||
|
|
@ -175,7 +175,9 @@ class RealtimeClient:
|
|||
|
||||
try:
|
||||
while self.is_active:
|
||||
audio_data = self.input_stream.read(CHUNK_SIZE, exception_on_overflow=False)
|
||||
audio_data = self.input_stream.read(
|
||||
CHUNK_SIZE, exception_on_overflow=False
|
||||
)
|
||||
await self.send_audio_chunk(audio_data)
|
||||
await asyncio.sleep(0.01) # Small delay to prevent overwhelming
|
||||
except Exception as e:
|
||||
|
|
@ -270,6 +272,7 @@ async def main():
|
|||
except Exception as e:
|
||||
print(f"\n❌ Error: {e}")
|
||||
import traceback
|
||||
|
||||
traceback.print_exc()
|
||||
finally:
|
||||
await client.close()
|
||||
|
|
@ -281,7 +284,7 @@ if __name__ == "__main__":
|
|||
print("2. Bedrock is configured in proxy_server_config.yaml")
|
||||
print("3. AWS credentials are set")
|
||||
print()
|
||||
|
||||
|
||||
try:
|
||||
asyncio.run(main())
|
||||
except KeyboardInterrupt:
|
||||
|
|
|
|||
|
|
@ -21,49 +21,45 @@ from typing import Optional
|
|||
|
||||
class VeoVideoGenerator:
|
||||
"""Complete Veo video generation client using LiteLLM proxy."""
|
||||
|
||||
def __init__(self, base_url: str = "http://localhost:4000/gemini/v1beta",
|
||||
api_key: str = "sk-1234"):
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
base_url: str = "http://localhost:4000/gemini/v1beta",
|
||||
api_key: str = "sk-1234",
|
||||
):
|
||||
"""
|
||||
Initialize the Veo video generator.
|
||||
|
||||
|
||||
Args:
|
||||
base_url: Base URL for the LiteLLM proxy with Gemini pass-through
|
||||
api_key: API key for LiteLLM proxy authentication
|
||||
"""
|
||||
self.base_url = base_url
|
||||
self.api_key = api_key
|
||||
self.headers = {
|
||||
"x-goog-api-key": api_key,
|
||||
"Content-Type": "application/json"
|
||||
}
|
||||
|
||||
self.headers = {"x-goog-api-key": api_key, "Content-Type": "application/json"}
|
||||
|
||||
def generate_video(self, prompt: str) -> Optional[str]:
|
||||
"""
|
||||
Initiate video generation with Veo.
|
||||
|
||||
|
||||
Args:
|
||||
prompt: Text description of the video to generate
|
||||
|
||||
|
||||
Returns:
|
||||
Operation name if successful, None otherwise
|
||||
"""
|
||||
print(f"🎬 Generating video with prompt: '{prompt}'")
|
||||
|
||||
|
||||
url = f"{self.base_url}/models/veo-3.0-generate-preview:predictLongRunning"
|
||||
payload = {
|
||||
"instances": [{
|
||||
"prompt": prompt
|
||||
}]
|
||||
}
|
||||
|
||||
payload = {"instances": [{"prompt": prompt}]}
|
||||
|
||||
try:
|
||||
response = requests.post(url, headers=self.headers, json=payload)
|
||||
response.raise_for_status()
|
||||
|
||||
|
||||
data = response.json()
|
||||
operation_name = data.get("name")
|
||||
|
||||
|
||||
if operation_name:
|
||||
print(f"✅ Video generation started: {operation_name}")
|
||||
return operation_name
|
||||
|
|
@ -71,58 +67,64 @@ class VeoVideoGenerator:
|
|||
print("❌ No operation name returned")
|
||||
print(f"Response: {json.dumps(data, indent=2)}")
|
||||
return None
|
||||
|
||||
|
||||
except requests.RequestException as e:
|
||||
print(f"❌ Failed to start video generation: {e}")
|
||||
if hasattr(e, 'response') and e.response is not None:
|
||||
if hasattr(e, "response") and e.response is not None:
|
||||
try:
|
||||
error_data = e.response.json()
|
||||
print(f"Error details: {json.dumps(error_data, indent=2)}")
|
||||
except:
|
||||
print(f"Error response: {e.response.text}")
|
||||
return None
|
||||
|
||||
def wait_for_completion(self, operation_name: str, max_wait_time: int = 600) -> Optional[str]:
|
||||
|
||||
def wait_for_completion(
|
||||
self, operation_name: str, max_wait_time: int = 600
|
||||
) -> Optional[str]:
|
||||
"""
|
||||
Poll operation status until video generation is complete.
|
||||
|
||||
|
||||
Args:
|
||||
operation_name: Name of the operation to monitor
|
||||
max_wait_time: Maximum time to wait in seconds (default: 10 minutes)
|
||||
|
||||
|
||||
Returns:
|
||||
Video URI if successful, None otherwise
|
||||
"""
|
||||
print("⏳ Waiting for video generation to complete...")
|
||||
|
||||
|
||||
operation_url = f"{self.base_url}/{operation_name}"
|
||||
start_time = time.time()
|
||||
poll_interval = 10 # Start with 10 seconds
|
||||
|
||||
|
||||
while time.time() - start_time < max_wait_time:
|
||||
try:
|
||||
print(f"🔍 Polling status... ({int(time.time() - start_time)}s elapsed)")
|
||||
|
||||
print(
|
||||
f"🔍 Polling status... ({int(time.time() - start_time)}s elapsed)"
|
||||
)
|
||||
|
||||
response = requests.get(operation_url, headers=self.headers)
|
||||
response.raise_for_status()
|
||||
|
||||
|
||||
data = response.json()
|
||||
|
||||
|
||||
# Check for errors
|
||||
if "error" in data:
|
||||
print("❌ Error in video generation:")
|
||||
print(json.dumps(data["error"], indent=2))
|
||||
return None
|
||||
|
||||
|
||||
# Check if operation is complete
|
||||
is_done = data.get("done", False)
|
||||
|
||||
|
||||
if is_done:
|
||||
print("🎉 Video generation complete!")
|
||||
|
||||
|
||||
try:
|
||||
# Extract video URI from nested response
|
||||
video_uri = data["response"]["generateVideoResponse"]["generatedSamples"][0]["video"]["uri"]
|
||||
video_uri = data["response"]["generateVideoResponse"][
|
||||
"generatedSamples"
|
||||
][0]["video"]["uri"]
|
||||
print(f"📹 Video URI: {video_uri}")
|
||||
return video_uri
|
||||
except KeyError as e:
|
||||
|
|
@ -130,64 +132,68 @@ class VeoVideoGenerator:
|
|||
print("Full response:")
|
||||
print(json.dumps(data, indent=2))
|
||||
return None
|
||||
|
||||
|
||||
# Wait before next poll, with exponential backoff
|
||||
time.sleep(poll_interval)
|
||||
poll_interval = min(poll_interval * 1.2, 30) # Cap at 30 seconds
|
||||
|
||||
|
||||
except requests.RequestException as e:
|
||||
print(f"❌ Error polling operation status: {e}")
|
||||
time.sleep(poll_interval)
|
||||
|
||||
|
||||
print(f"⏰ Timeout after {max_wait_time} seconds")
|
||||
return None
|
||||
|
||||
def download_video(self, video_uri: str, output_filename: str = "generated_video.mp4") -> bool:
|
||||
|
||||
def download_video(
|
||||
self, video_uri: str, output_filename: str = "generated_video.mp4"
|
||||
) -> bool:
|
||||
"""
|
||||
Download the generated video file.
|
||||
|
||||
|
||||
Args:
|
||||
video_uri: URI of the video to download (from Google's response)
|
||||
output_filename: Local filename to save the video
|
||||
|
||||
|
||||
Returns:
|
||||
True if download successful, False otherwise
|
||||
"""
|
||||
print(f"⬇️ Downloading video...")
|
||||
print(f"Original URI: {video_uri}")
|
||||
|
||||
|
||||
# Convert Google URI to LiteLLM proxy URI
|
||||
# Example: files/abc123 -> /gemini/v1beta/files/abc123:download?alt=media
|
||||
if video_uri.startswith("files/"):
|
||||
download_path = f"{video_uri}:download?alt=media"
|
||||
else:
|
||||
download_path = video_uri
|
||||
|
||||
|
||||
litellm_download_url = f"{self.base_url}/{download_path}"
|
||||
print(f"Download URL: {litellm_download_url}")
|
||||
|
||||
|
||||
try:
|
||||
# Download with streaming and redirect handling
|
||||
response = requests.get(
|
||||
litellm_download_url,
|
||||
headers=self.headers,
|
||||
litellm_download_url,
|
||||
headers=self.headers,
|
||||
stream=True,
|
||||
allow_redirects=True # Handle redirects automatically
|
||||
allow_redirects=True, # Handle redirects automatically
|
||||
)
|
||||
response.raise_for_status()
|
||||
|
||||
|
||||
# Save video file
|
||||
with open(output_filename, 'wb') as f:
|
||||
with open(output_filename, "wb") as f:
|
||||
downloaded_size = 0
|
||||
for chunk in response.iter_content(chunk_size=8192):
|
||||
if chunk:
|
||||
f.write(chunk)
|
||||
downloaded_size += len(chunk)
|
||||
|
||||
|
||||
# Progress indicator for large files
|
||||
if downloaded_size % (1024 * 1024) == 0: # Every MB
|
||||
print(f"📦 Downloaded {downloaded_size / (1024*1024):.1f} MB...")
|
||||
|
||||
print(
|
||||
f"📦 Downloaded {downloaded_size / (1024*1024):.1f} MB..."
|
||||
)
|
||||
|
||||
# Verify file was created and has content
|
||||
if os.path.exists(output_filename):
|
||||
file_size = os.path.getsize(output_filename)
|
||||
|
|
@ -203,48 +209,52 @@ class VeoVideoGenerator:
|
|||
else:
|
||||
print("❌ File was not created")
|
||||
return False
|
||||
|
||||
|
||||
except requests.RequestException as e:
|
||||
print(f"❌ Download failed: {e}")
|
||||
if hasattr(e, 'response') and e.response is not None:
|
||||
if hasattr(e, "response") and e.response is not None:
|
||||
print(f"Status code: {e.response.status_code}")
|
||||
print(f"Response headers: {dict(e.response.headers)}")
|
||||
return False
|
||||
|
||||
|
||||
def generate_and_download(self, prompt: str, output_filename: str = None) -> bool:
|
||||
"""
|
||||
Complete workflow: generate video and download it.
|
||||
|
||||
|
||||
Args:
|
||||
prompt: Text description for video generation
|
||||
output_filename: Output filename (auto-generated if None)
|
||||
|
||||
|
||||
Returns:
|
||||
True if successful, False otherwise
|
||||
"""
|
||||
# Auto-generate filename if not provided
|
||||
if output_filename is None:
|
||||
timestamp = int(time.time())
|
||||
safe_prompt = "".join(c for c in prompt[:30] if c.isalnum() or c in (' ', '-', '_')).rstrip()
|
||||
output_filename = f"veo_video_{safe_prompt.replace(' ', '_')}_{timestamp}.mp4"
|
||||
|
||||
safe_prompt = "".join(
|
||||
c for c in prompt[:30] if c.isalnum() or c in (" ", "-", "_")
|
||||
).rstrip()
|
||||
output_filename = (
|
||||
f"veo_video_{safe_prompt.replace(' ', '_')}_{timestamp}.mp4"
|
||||
)
|
||||
|
||||
print("=" * 60)
|
||||
print("🎬 VEO VIDEO GENERATION WORKFLOW")
|
||||
print("=" * 60)
|
||||
|
||||
|
||||
# Step 1: Generate video
|
||||
operation_name = self.generate_video(prompt)
|
||||
if not operation_name:
|
||||
return False
|
||||
|
||||
|
||||
# Step 2: Wait for completion
|
||||
video_uri = self.wait_for_completion(operation_name)
|
||||
if not video_uri:
|
||||
return False
|
||||
|
||||
|
||||
# Step 3: Download video
|
||||
success = self.download_video(video_uri, output_filename)
|
||||
|
||||
|
||||
if success:
|
||||
print("=" * 60)
|
||||
print("🎉 SUCCESS! Video generation complete!")
|
||||
|
|
@ -254,51 +264,51 @@ class VeoVideoGenerator:
|
|||
print("=" * 60)
|
||||
print("❌ FAILED! Video generation or download failed")
|
||||
print("=" * 60)
|
||||
|
||||
|
||||
return success
|
||||
|
||||
|
||||
def main():
|
||||
"""
|
||||
Example usage of the VeoVideoGenerator.
|
||||
|
||||
|
||||
Configure these environment variables:
|
||||
- LITELLM_BASE_URL: Your LiteLLM proxy URL (default: http://localhost:4000/gemini/v1beta)
|
||||
- LITELLM_API_KEY: Your LiteLLM API key (default: sk-1234)
|
||||
"""
|
||||
|
||||
|
||||
# Configuration from environment or defaults
|
||||
base_url = os.getenv("LITELLM_BASE_URL", "http://localhost:4000/gemini/v1beta")
|
||||
api_key = os.getenv("LITELLM_API_KEY", "sk-1234")
|
||||
|
||||
|
||||
print("🚀 Starting Veo Video Generation Example")
|
||||
print(f"📡 Using LiteLLM proxy at: {base_url}")
|
||||
|
||||
|
||||
# Initialize generator
|
||||
generator = VeoVideoGenerator(base_url=base_url, api_key=api_key)
|
||||
|
||||
|
||||
# Example prompts - try different ones!
|
||||
example_prompts = [
|
||||
"A cat playing with a ball of yarn in a sunny garden",
|
||||
"Ocean waves crashing against rocky cliffs at sunset",
|
||||
"A bustling city street with people walking and cars passing by",
|
||||
"A peaceful forest with sunlight filtering through the trees"
|
||||
"A peaceful forest with sunlight filtering through the trees",
|
||||
]
|
||||
|
||||
|
||||
# Use first example or get from user
|
||||
prompt = example_prompts[0]
|
||||
print(f"🎬 Using prompt: '{prompt}'")
|
||||
|
||||
|
||||
# Generate and download video
|
||||
success = generator.generate_and_download(prompt)
|
||||
|
||||
|
||||
if success:
|
||||
print("\n✅ Example completed successfully!")
|
||||
print("💡 Try modifying the prompt in the script for different videos!")
|
||||
else:
|
||||
print("\n❌ Example failed!")
|
||||
print("🔧 Check your LiteLLM proxy configuration and Google AI Studio API key")
|
||||
|
||||
|
||||
# Troubleshooting tips
|
||||
print("\n🔍 Troubleshooting:")
|
||||
print("1. Ensure LiteLLM proxy is running with Google AI Studio pass-through")
|
||||
|
|
|
|||
4
cosign.pub
Normal file
4
cosign.pub
Normal file
|
|
@ -0,0 +1,4 @@
|
|||
-----BEGIN PUBLIC KEY-----
|
||||
MFkwEwYHKoZIzj0CAQYIKoZIzj0DAQcDQgAEKi4ivqGpE231OGH50PKbqy1Y1Kkb
|
||||
POJC8+i2Wko82gBOUCe3M0Vw86H/4rhUhfoYEti4gdJ9wZbYmK0I2EE96g==
|
||||
-----END PUBLIC KEY-----
|
||||
|
|
@ -1,5 +1,5 @@
|
|||
# Use the provided base image
|
||||
FROM ghcr.io/berriai/litellm:main-latest
|
||||
FROM ghcr.io/berriai/litellm:main-latest@sha256:7c311546c25e7bb6e8cafede9fcd3d0d622ac636b5c9418befaa32e85dfb0186
|
||||
|
||||
# Set the working directory to /app
|
||||
WORKDIR /app
|
||||
|
|
|
|||
|
|
@ -47,7 +47,7 @@ spec:
|
|||
{{- toYaml .Values.podSecurityContext | nindent 8 }}
|
||||
{{- with .Values.extraInitContainers }}
|
||||
initContainers:
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- tpl (toYaml .) $ | nindent 8 }}
|
||||
{{- end }}
|
||||
containers:
|
||||
- name: {{ include "litellm.name" . }}
|
||||
|
|
@ -212,7 +212,7 @@ spec:
|
|||
{{- toYaml . | nindent 12 }}
|
||||
{{- end }}
|
||||
{{- with .Values.extraContainers }}
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- tpl (toYaml .) $ | nindent 8 }}
|
||||
{{- end }}
|
||||
volumes:
|
||||
{{ if .Values.securityContext.readOnlyRootFilesystem }}
|
||||
|
|
|
|||
|
|
@ -37,7 +37,7 @@ spec:
|
|||
serviceAccountName: {{ include "litellm.migrationServiceAccountName" . }}
|
||||
{{- with .Values.migrationJob.extraInitContainers }}
|
||||
initContainers:
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- tpl (toYaml .) $ | nindent 8 }}
|
||||
{{- end }}
|
||||
containers:
|
||||
- name: prisma-migrations
|
||||
|
|
@ -96,7 +96,7 @@ spec:
|
|||
{{- toYaml . | nindent 12 }}
|
||||
{{- end }}
|
||||
{{- with .Values.migrationJob.extraContainers }}
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- tpl (toYaml .) $ | nindent 8 }}
|
||||
{{- end }}
|
||||
{{- with .Values.volumes }}
|
||||
volumes:
|
||||
|
|
|
|||
|
|
@ -319,3 +319,61 @@ tests:
|
|||
asserts:
|
||||
- notExists:
|
||||
path: spec.minReadySeconds
|
||||
- it: should work with extraInitContainers
|
||||
template: deployment.yaml
|
||||
set:
|
||||
extraInitContainers:
|
||||
- name: init-test
|
||||
image: busybox:latest
|
||||
command: ["echo", "hello"]
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.initContainers
|
||||
content:
|
||||
name: init-test
|
||||
image: busybox:latest
|
||||
command: ["echo", "hello"]
|
||||
- it: should support tpl in extraInitContainers
|
||||
template: deployment.yaml
|
||||
set:
|
||||
image:
|
||||
repository: ghcr.io/berriai/litellm-database
|
||||
tag: test
|
||||
extraInitContainers:
|
||||
- name: init-tpl
|
||||
image: "{{ .Values.image.repository }}:{{ .Values.image.tag }}"
|
||||
command: ["echo", "hello"]
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.initContainers
|
||||
content:
|
||||
name: init-tpl
|
||||
image: "ghcr.io/berriai/litellm-database:test"
|
||||
command: ["echo", "hello"]
|
||||
- it: should work with extraContainers
|
||||
template: deployment.yaml
|
||||
set:
|
||||
extraContainers:
|
||||
- name: sidecar
|
||||
image: busybox:latest
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.containers
|
||||
content:
|
||||
name: sidecar
|
||||
image: busybox:latest
|
||||
- it: should support tpl in extraContainers
|
||||
template: deployment.yaml
|
||||
set:
|
||||
image:
|
||||
repository: ghcr.io/berriai/litellm-database
|
||||
tag: test
|
||||
extraContainers:
|
||||
- name: sidecar-tpl
|
||||
image: "{{ .Values.image.repository }}:{{ .Values.image.tag }}"
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.containers
|
||||
content:
|
||||
name: sidecar-tpl
|
||||
image: "ghcr.io/berriai/litellm-database:test"
|
||||
|
|
|
|||
|
|
@ -188,3 +188,69 @@ tests:
|
|||
- equal:
|
||||
path: spec.template.spec.serviceAccountName
|
||||
value: pre-existing-sa
|
||||
- it: should work with extraInitContainers
|
||||
template: migrations-job.yaml
|
||||
set:
|
||||
migrationJob:
|
||||
enabled: true
|
||||
extraInitContainers:
|
||||
- name: init-test
|
||||
image: busybox:latest
|
||||
command: ["echo", "hello"]
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.initContainers
|
||||
content:
|
||||
name: init-test
|
||||
image: busybox:latest
|
||||
command: ["echo", "hello"]
|
||||
- it: should support tpl in extraInitContainers
|
||||
template: migrations-job.yaml
|
||||
set:
|
||||
image:
|
||||
repository: ghcr.io/berriai/litellm-database
|
||||
tag: test
|
||||
migrationJob:
|
||||
enabled: true
|
||||
extraInitContainers:
|
||||
- name: init-tpl
|
||||
image: "{{ .Values.image.repository }}:{{ .Values.image.tag }}"
|
||||
command: ["echo", "hello"]
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.initContainers
|
||||
content:
|
||||
name: init-tpl
|
||||
image: "ghcr.io/berriai/litellm-database:test"
|
||||
command: ["echo", "hello"]
|
||||
- it: should work with extraContainers
|
||||
template: migrations-job.yaml
|
||||
set:
|
||||
migrationJob:
|
||||
enabled: true
|
||||
extraContainers:
|
||||
- name: sidecar
|
||||
image: busybox:latest
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.containers
|
||||
content:
|
||||
name: sidecar
|
||||
image: busybox:latest
|
||||
- it: should support tpl in extraContainers
|
||||
template: migrations-job.yaml
|
||||
set:
|
||||
image:
|
||||
repository: ghcr.io/berriai/litellm-database
|
||||
tag: test
|
||||
migrationJob:
|
||||
enabled: true
|
||||
extraContainers:
|
||||
- name: sidecar-tpl
|
||||
image: "{{ .Values.image.repository }}:{{ .Values.image.tag }}"
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.containers
|
||||
content:
|
||||
name: sidecar-tpl
|
||||
image: "ghcr.io/berriai/litellm-database:test"
|
||||
|
|
|
|||
|
|
@ -1,57 +1,68 @@
|
|||
# Base image for building
|
||||
ARG LITELLM_BUILD_IMAGE=python:3.11-alpine
|
||||
ARG LITELLM_BUILD_IMAGE=python:3.11-alpine@sha256:f07e2ace46f560f09a6eeec7b4913b80ee99546e749ef82342a419a326620856
|
||||
|
||||
# Runtime image
|
||||
ARG LITELLM_RUNTIME_IMAGE=python:3.11-alpine
|
||||
ARG LITELLM_RUNTIME_IMAGE=python:3.11-alpine@sha256:f07e2ace46f560f09a6eeec7b4913b80ee99546e749ef82342a419a326620856
|
||||
ARG UV_IMAGE=ghcr.io/astral-sh/uv:0.10.9@sha256:10902f58a1606787602f303954cea099626a4adb02acbac4c69920fe9d278f82
|
||||
|
||||
FROM $UV_IMAGE AS uvbin
|
||||
|
||||
# Builder stage
|
||||
FROM $LITELLM_BUILD_IMAGE AS builder
|
||||
|
||||
# Set the working directory to /app
|
||||
WORKDIR /app
|
||||
|
||||
# Install build dependencies
|
||||
RUN apk add --no-cache gcc python3-dev musl-dev
|
||||
COPY --from=uvbin /uv /usr/local/bin/uv
|
||||
COPY --from=uvbin /uvx /usr/local/bin/uvx
|
||||
|
||||
RUN pip install --upgrade pip && \
|
||||
pip install build
|
||||
RUN apk add --no-cache gcc python3-dev musl-dev nodejs npm libsndfile
|
||||
|
||||
# Copy the current directory contents into the container at /app
|
||||
ENV PRISMA_BINARY_CACHE_DIR=/app/.cache/prisma-python/binaries \
|
||||
UV_PROJECT_ENVIRONMENT=/app/.venv \
|
||||
UV_LINK_MODE=copy \
|
||||
XDG_CACHE_HOME=/app/.cache \
|
||||
PATH="/app/.venv/bin:${PATH}"
|
||||
|
||||
# Copy dependency metadata first for layer caching
|
||||
COPY pyproject.toml uv.lock ./
|
||||
COPY enterprise/pyproject.toml enterprise/
|
||||
COPY litellm-proxy-extras/pyproject.toml litellm-proxy-extras/
|
||||
|
||||
# Install third-party dependencies (cached unless pyproject.toml/uv.lock change)
|
||||
RUN uv sync --frozen --no-install-project --no-install-workspace --no-default-groups --no-editable \
|
||||
--extra proxy \
|
||||
--extra proxy-runtime \
|
||||
--extra extra_proxy \
|
||||
--extra semantic-router \
|
||||
--python python3
|
||||
|
||||
# Copy full source tree
|
||||
COPY . .
|
||||
|
||||
# Build the package
|
||||
RUN rm -rf dist/* && python -m build
|
||||
# Install project and workspace packages (fast - deps already cached)
|
||||
RUN uv sync --frozen --no-default-groups --no-editable \
|
||||
--extra proxy \
|
||||
--extra proxy-runtime \
|
||||
--extra extra_proxy \
|
||||
--extra semantic-router \
|
||||
--python python3
|
||||
|
||||
# There should be only one wheel file now, assume the build only creates one
|
||||
RUN ls -1 dist/*.whl | head -1
|
||||
RUN prisma generate --schema=./schema.prisma
|
||||
|
||||
# Install the package
|
||||
RUN pip install dist/*.whl
|
||||
RUN sed -i 's/\r$//' docker/entrypoint.sh && chmod +x docker/entrypoint.sh && \
|
||||
sed -i 's/\r$//' docker/prod_entrypoint.sh && chmod +x docker/prod_entrypoint.sh
|
||||
|
||||
# install dependencies as wheels
|
||||
RUN pip wheel --no-cache-dir --wheel-dir=/wheels/ -r requirements.txt
|
||||
|
||||
# Runtime stage
|
||||
FROM $LITELLM_RUNTIME_IMAGE AS runtime
|
||||
|
||||
# Update dependencies and clean up, install libsndfile for audio processing
|
||||
RUN apk upgrade --no-cache && apk add --no-cache libsndfile
|
||||
RUN apk upgrade --no-cache && apk add --no-cache libsndfile nodejs npm
|
||||
|
||||
WORKDIR /app
|
||||
ENV PRISMA_BINARY_CACHE_DIR=/app/.cache/prisma-python/binaries \
|
||||
XDG_CACHE_HOME=/app/.cache \
|
||||
PATH="/app/.venv/bin:${PATH}"
|
||||
|
||||
# Copy the built wheel from the builder stage to the runtime stage; assumes only one wheel file is present
|
||||
COPY --from=builder /app/dist/*.whl .
|
||||
COPY --from=builder /wheels/ /wheels/
|
||||
|
||||
# Install the built wheel using pip; again using a wildcard if it's the only file
|
||||
RUN pip install *.whl /wheels/* --no-index --find-links=/wheels/ && rm -f *.whl && rm -rf /wheels
|
||||
|
||||
# Convert Windows line endings to Unix for entrypoint scripts
|
||||
RUN sed -i 's/\r$//' docker/entrypoint.sh && chmod +x docker/entrypoint.sh
|
||||
RUN sed -i 's/\r$//' docker/prod_entrypoint.sh && chmod +x docker/prod_entrypoint.sh
|
||||
COPY --from=builder /app /app
|
||||
|
||||
EXPOSE 4000/tcp
|
||||
|
||||
# Set your entrypoint and command
|
||||
ENTRYPOINT ["docker/prod_entrypoint.sh"]
|
||||
CMD ["--port", "4000"]
|
||||
|
|
|
|||
|
|
@ -1,4 +1,5 @@
|
|||
# Use the provided base image
|
||||
# NOTE: This is a dev/branch-specific tag. Update digest when the base image is rebuilt.
|
||||
FROM ghcr.io/berriai/litellm:litellm_fwd_server_root_path-dev
|
||||
|
||||
# Set the working directory to /app
|
||||
|
|
@ -18,8 +19,8 @@ RUN apt-get update && apt-get upgrade -y \
|
|||
libxslt1.1 \
|
||||
libgnutls30 \
|
||||
libc6 && \
|
||||
apt-get install -y nodejs npm && \
|
||||
npm install -g npm@latest tar@7.5.11 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 && \
|
||||
apt-get install -y --no-install-recommends nodejs npm && \
|
||||
npm install -g npm@11.12.1 tar@7.5.11 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 && \
|
||||
GLOBAL="$(npm root -g)" && \
|
||||
find "$GLOBAL/npm" -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
|
|
@ -51,7 +52,7 @@ ENV UI_BASE_PATH="/prod/ui"
|
|||
|
||||
# Build the UI with the specified UI_BASE_PATH
|
||||
WORKDIR /app/ui/litellm-dashboard
|
||||
RUN npm install
|
||||
RUN npm ci
|
||||
RUN UI_BASE_PATH=$UI_BASE_PATH npm run build
|
||||
|
||||
# Create the destination directory
|
||||
|
|
@ -70,8 +71,16 @@ WORKDIR /app
|
|||
RUN sed -i 's/\r$//' docker/entrypoint.sh && chmod +x docker/entrypoint.sh
|
||||
RUN sed -i 's/\r$//' docker/prod_entrypoint.sh && chmod +x docker/prod_entrypoint.sh
|
||||
|
||||
# Run as non-root user
|
||||
RUN groupadd --gid 1000 appuser && useradd --uid 1000 --gid 1000 --no-create-home appuser \
|
||||
&& chown -R appuser:appuser /app
|
||||
USER appuser
|
||||
|
||||
# Expose the necessary port
|
||||
EXPOSE 4000/tcp
|
||||
|
||||
HEALTHCHECK --interval=30s --timeout=5s --start-period=10s --retries=3 \
|
||||
CMD ["python", "-c", "import urllib.request; urllib.request.urlopen('http://localhost:4000/health')"]
|
||||
|
||||
# Override the CMD instruction with your desired command and arguments
|
||||
CMD ["--port", "4000", "--config", "config.yaml", "--detailed_debug"]
|
||||
|
|
@ -1,56 +1,73 @@
|
|||
# Base image for building
|
||||
ARG LITELLM_BUILD_IMAGE=cgr.dev/chainguard/wolfi-base
|
||||
ARG LITELLM_BUILD_IMAGE=cgr.dev/chainguard/wolfi-base@sha256:a5a619c1793039dcf92f02178f37c94bb3d6001403716da59d6092dfe8d9b502
|
||||
|
||||
# Runtime image
|
||||
ARG LITELLM_RUNTIME_IMAGE=cgr.dev/chainguard/wolfi-base
|
||||
# Builder stage
|
||||
ARG LITELLM_RUNTIME_IMAGE=cgr.dev/chainguard/wolfi-base@sha256:a5a619c1793039dcf92f02178f37c94bb3d6001403716da59d6092dfe8d9b502
|
||||
ARG UV_IMAGE=ghcr.io/astral-sh/uv:0.10.9@sha256:10902f58a1606787602f303954cea099626a4adb02acbac4c69920fe9d278f82
|
||||
|
||||
FROM $UV_IMAGE AS uvbin
|
||||
|
||||
FROM $LITELLM_BUILD_IMAGE AS builder
|
||||
|
||||
# Set the working directory to /app
|
||||
WORKDIR /app
|
||||
|
||||
USER root
|
||||
|
||||
# Install build dependencies
|
||||
COPY --from=uvbin /uv /usr/local/bin/uv
|
||||
COPY --from=uvbin /uvx /usr/local/bin/uvx
|
||||
|
||||
RUN apk add --no-cache \
|
||||
bash \
|
||||
gcc \
|
||||
py3-pip \
|
||||
python3 \
|
||||
python3-dev \
|
||||
openssl \
|
||||
openssl-dev
|
||||
openssl-dev \
|
||||
nodejs \
|
||||
npm \
|
||||
libsndfile
|
||||
|
||||
RUN python -m pip install build
|
||||
ENV UV_PROJECT_ENVIRONMENT=/app/.venv \
|
||||
UV_LINK_MODE=copy \
|
||||
PATH="/app/.venv/bin:${PATH}"
|
||||
|
||||
# Copy the current directory contents into the container at /app
|
||||
# Copy dependency metadata first for layer caching
|
||||
COPY pyproject.toml uv.lock ./
|
||||
COPY enterprise/pyproject.toml enterprise/
|
||||
COPY litellm-proxy-extras/pyproject.toml litellm-proxy-extras/
|
||||
|
||||
# Install third-party dependencies (cached unless pyproject.toml/uv.lock change)
|
||||
RUN uv sync --frozen --no-install-project --no-install-workspace --no-default-groups --no-editable \
|
||||
--extra proxy \
|
||||
--extra proxy-runtime \
|
||||
--extra extra_proxy \
|
||||
--extra semantic-router \
|
||||
--python python3
|
||||
|
||||
# Copy full source tree
|
||||
COPY . .
|
||||
|
||||
# Build Admin UI
|
||||
# Convert Windows line endings to Unix and make executable
|
||||
# Build Admin UI before final sync
|
||||
RUN sed -i 's/\r$//' docker/build_admin_ui.sh && chmod +x docker/build_admin_ui.sh && ./docker/build_admin_ui.sh
|
||||
|
||||
# Build the package
|
||||
RUN rm -rf dist/* && python -m build
|
||||
# Install project and workspace packages (fast - deps already cached)
|
||||
RUN uv sync --frozen --no-default-groups --no-editable \
|
||||
--extra proxy \
|
||||
--extra proxy-runtime \
|
||||
--extra extra_proxy \
|
||||
--extra semantic-router \
|
||||
--python python3
|
||||
|
||||
# There should be only one wheel file now, assume the build only creates one
|
||||
RUN ls -1 dist/*.whl | head -1
|
||||
RUN prisma generate --schema=./schema.prisma
|
||||
|
||||
# Install the package
|
||||
RUN pip install dist/*.whl
|
||||
RUN sed -i 's/\r$//' docker/entrypoint.sh && chmod +x docker/entrypoint.sh && \
|
||||
sed -i 's/\r$//' docker/prod_entrypoint.sh && chmod +x docker/prod_entrypoint.sh
|
||||
|
||||
# install dependencies as wheels
|
||||
RUN pip wheel --no-cache-dir --wheel-dir=/wheels/ -r requirements.txt
|
||||
|
||||
# Runtime stage
|
||||
FROM $LITELLM_RUNTIME_IMAGE AS runtime
|
||||
|
||||
# Ensure runtime stage runs as root
|
||||
USER root
|
||||
|
||||
# Install runtime dependencies
|
||||
RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip libsndfile && \
|
||||
npm install -g npm@latest tar@7.5.11 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 && \
|
||||
RUN apk add --no-cache bash openssl tzdata nodejs npm python3 libsndfile supervisor && \
|
||||
npm install -g npm@11.12.1 tar@7.5.11 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 && \
|
||||
GLOBAL="$(npm root -g)" && \
|
||||
find "$GLOBAL/npm" -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
|
|
@ -73,66 +90,21 @@ RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip libsndfile
|
|||
{ apk del --no-cache npm 2>/dev/null || true; }
|
||||
|
||||
WORKDIR /app
|
||||
# Copy the current directory contents into the container at /app
|
||||
COPY . .
|
||||
RUN ls -la /app
|
||||
ENV PATH="/app/.venv/bin:${PATH}"
|
||||
|
||||
# Copy the built wheel from the builder stage to the runtime stage; assumes only one wheel file is present
|
||||
COPY --from=builder /app/dist/*.whl .
|
||||
COPY --from=builder /wheels/ /wheels/
|
||||
COPY --from=builder /app /app
|
||||
# Prisma binaries live in $HOME/.cache (default prisma-python location),
|
||||
# which is /root/.cache here. Copy them from the builder so they survive
|
||||
# deployments that volume-mount /app/.cache (e.g. readOnlyRootFilesystem
|
||||
# + emptyDir) — otherwise the mount would shadow the baked-in query engine.
|
||||
COPY --from=builder /root/.cache /root/.cache
|
||||
|
||||
# Install the built wheel using pip; again using a wildcard if it's the only file
|
||||
RUN pip install *.whl /wheels/* --no-index --find-links=/wheels/ && rm -f *.whl && rm -rf /wheels
|
||||
RUN find /app/.venv -type f -path "*/tornado/test/*" -delete && \
|
||||
find /app/.venv -type d -path "*/tornado/test" -delete
|
||||
|
||||
# SECURITY FIX: nodejs-wheel-binaries (pip package used by Prisma) bundles a complete
|
||||
# npm with old vulnerable deps at /usr/lib/python3.*/site-packages/nodejs_wheel/.
|
||||
# Patch every copy of tar, glob, and brace-expansion inside that tree.
|
||||
RUN GLOBAL="$(npm root -g)" && \
|
||||
[ -n "$GLOBAL" ] || { echo "ERROR: npm root -g returned empty; aborting"; exit 1; } && \
|
||||
find /usr/lib -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "glob" -path "*/node_modules/glob" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/glob" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "brace-expansion" -path "*/node_modules/@isaacs/brace-expansion" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/@isaacs/brace-expansion" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "minimatch" -path "*/node_modules/minimatch" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/minimatch" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "diff" -path "*/node_modules/diff" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/diff" "$d"; \
|
||||
done
|
||||
|
||||
# Install semantic_router and aurelio-sdk using script
|
||||
# Convert Windows line endings to Unix and make executable
|
||||
RUN sed -i 's/\r$//' docker/install_auto_router.sh && chmod +x docker/install_auto_router.sh && ./docker/install_auto_router.sh
|
||||
|
||||
# ensure pyjwt is used, not jwt
|
||||
RUN pip uninstall jwt -y
|
||||
RUN pip uninstall PyJWT -y
|
||||
RUN pip install PyJWT==2.12.0 --no-cache-dir
|
||||
|
||||
# Build Admin UI (runtime stage)
|
||||
# Convert Windows line endings to Unix and make executable
|
||||
RUN sed -i 's/\r$//' docker/build_admin_ui.sh && chmod +x docker/build_admin_ui.sh && ./docker/build_admin_ui.sh
|
||||
|
||||
# Generate prisma client
|
||||
RUN prisma generate
|
||||
# Convert Windows line endings to Unix for entrypoint scripts
|
||||
RUN sed -i 's/\r$//' docker/entrypoint.sh && chmod +x docker/entrypoint.sh
|
||||
RUN sed -i 's/\r$//' docker/prod_entrypoint.sh && chmod +x docker/prod_entrypoint.sh
|
||||
EXPOSE 4000/tcp
|
||||
|
||||
RUN apk add --no-cache supervisor
|
||||
COPY docker/supervisord.conf /etc/supervisord.conf
|
||||
|
||||
# # Set your entrypoint and command
|
||||
|
||||
|
||||
ENTRYPOINT ["docker/prod_entrypoint.sh"]
|
||||
|
||||
# Append "--detailed_debug" to the end of CMD to view detailed debug logs
|
||||
# CMD ["--port", "4000", "--detailed_debug"]
|
||||
CMD ["--port", "4000"]
|
||||
|
|
|
|||
|
|
@ -1,61 +1,72 @@
|
|||
# Base image for building
|
||||
ARG LITELLM_BUILD_IMAGE=python:3.11-slim
|
||||
ARG LITELLM_BUILD_IMAGE=python:3.13-slim@sha256:739e7213785e88c0f702dcdc12c0973afcbd606dbf021a589cab77d6b00b579d
|
||||
|
||||
# Runtime image
|
||||
ARG LITELLM_RUNTIME_IMAGE=python:3.11-slim
|
||||
ARG LITELLM_RUNTIME_IMAGE=python:3.13-slim@sha256:739e7213785e88c0f702dcdc12c0973afcbd606dbf021a589cab77d6b00b579d
|
||||
ARG UV_IMAGE=ghcr.io/astral-sh/uv:0.10.9@sha256:10902f58a1606787602f303954cea099626a4adb02acbac4c69920fe9d278f82
|
||||
|
||||
FROM $UV_IMAGE AS uvbin
|
||||
|
||||
# Builder stage
|
||||
FROM $LITELLM_BUILD_IMAGE AS builder
|
||||
|
||||
# Set the working directory to /app
|
||||
WORKDIR /app
|
||||
|
||||
USER root
|
||||
|
||||
# Install build dependencies in one layer
|
||||
COPY --from=uvbin /uv /usr/local/bin/uv
|
||||
COPY --from=uvbin /uvx /usr/local/bin/uvx
|
||||
|
||||
RUN apt-get update && apt-get install -y --no-install-recommends \
|
||||
gcc \
|
||||
g++ \
|
||||
python3-dev \
|
||||
libssl-dev \
|
||||
pkg-config \
|
||||
&& rm -rf /var/lib/apt/lists/* \
|
||||
&& pip install --upgrade pip build
|
||||
nodejs \
|
||||
npm \
|
||||
&& rm -rf /var/lib/apt/lists/*
|
||||
|
||||
# Copy requirements first for better layer caching
|
||||
COPY requirements.txt .
|
||||
ENV PRISMA_BINARY_CACHE_DIR=/app/.cache/prisma-python/binaries \
|
||||
UV_PROJECT_ENVIRONMENT=/app/.venv \
|
||||
UV_LINK_MODE=copy \
|
||||
XDG_CACHE_HOME=/app/.cache \
|
||||
PATH="/app/.venv/bin:${PATH}"
|
||||
|
||||
# Install Python dependencies with cache mount for faster rebuilds
|
||||
RUN --mount=type=cache,target=/root/.cache/pip \
|
||||
pip wheel --no-cache-dir --wheel-dir=/wheels/ -r requirements.txt
|
||||
# Copy dependency metadata first for layer caching
|
||||
COPY pyproject.toml uv.lock ./
|
||||
COPY enterprise/pyproject.toml enterprise/
|
||||
COPY litellm-proxy-extras/pyproject.toml litellm-proxy-extras/
|
||||
|
||||
# Fix JWT dependency conflicts early
|
||||
RUN pip uninstall jwt -y || true && \
|
||||
pip uninstall PyJWT -y || true && \
|
||||
pip install PyJWT==2.12.0 --no-cache-dir
|
||||
# Install third-party dependencies (cached unless pyproject.toml/uv.lock change)
|
||||
RUN uv sync --frozen --no-install-project --no-install-workspace --no-default-groups --no-editable \
|
||||
--extra proxy \
|
||||
--extra proxy-runtime \
|
||||
--extra extra_proxy \
|
||||
--extra semantic-router \
|
||||
--python python
|
||||
|
||||
# Copy only necessary files for build
|
||||
COPY pyproject.toml README.md schema.prisma poetry.lock ./
|
||||
COPY litellm/ ./litellm/
|
||||
COPY enterprise/ ./enterprise/
|
||||
COPY docker/ ./docker/
|
||||
# Copy full source tree
|
||||
COPY . .
|
||||
|
||||
# Build Admin UI once
|
||||
# Convert Windows line endings to Unix and make executable
|
||||
# Build Admin UI before final sync
|
||||
RUN sed -i 's/\r$//' docker/build_admin_ui.sh && chmod +x docker/build_admin_ui.sh && ./docker/build_admin_ui.sh
|
||||
|
||||
# Build the package
|
||||
RUN rm -rf dist/* && python -m build
|
||||
# Install project and workspace packages (fast - deps already cached)
|
||||
RUN uv sync --frozen --no-default-groups --no-editable \
|
||||
--extra proxy \
|
||||
--extra proxy-runtime \
|
||||
--extra extra_proxy \
|
||||
--extra semantic-router \
|
||||
--python python
|
||||
|
||||
# Install the built package
|
||||
RUN pip install dist/*.whl
|
||||
RUN prisma generate --schema=./schema.prisma
|
||||
|
||||
RUN sed -i 's/\r$//' docker/entrypoint.sh && chmod +x docker/entrypoint.sh && \
|
||||
sed -i 's/\r$//' docker/prod_entrypoint.sh && chmod +x docker/prod_entrypoint.sh
|
||||
|
||||
# Runtime stage
|
||||
FROM $LITELLM_RUNTIME_IMAGE AS runtime
|
||||
|
||||
# Ensure runtime stage runs as root
|
||||
USER root
|
||||
|
||||
# Install only runtime dependencies
|
||||
RUN apt-get update && apt-get upgrade -y \
|
||||
libxml2 \
|
||||
libexpat1 \
|
||||
|
|
@ -71,11 +82,11 @@ RUN apt-get update && apt-get upgrade -y \
|
|||
libc6 \
|
||||
&& apt-get install -y --no-install-recommends \
|
||||
libssl3 \
|
||||
libatomic1 \
|
||||
nodejs \
|
||||
npm \
|
||||
libatomic1 \
|
||||
nodejs \
|
||||
npm \
|
||||
&& rm -rf /var/lib/apt/lists/* \
|
||||
&& npm install -g npm@latest tar@7.5.11 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 \
|
||||
&& npm install -g npm@11.12.1 tar@7.5.11 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 \
|
||||
&& GLOBAL="$(npm root -g)" \
|
||||
&& find "$GLOBAL/npm" -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
|
|
@ -98,53 +109,13 @@ RUN apt-get update && apt-get upgrade -y \
|
|||
&& apt-get purge -y npm
|
||||
|
||||
WORKDIR /app
|
||||
ENV PRISMA_BINARY_CACHE_DIR=/app/.cache/prisma-python/binaries \
|
||||
XDG_CACHE_HOME=/app/.cache \
|
||||
PATH="/app/.venv/bin:${PATH}"
|
||||
|
||||
# Copy only necessary runtime files
|
||||
COPY docker/entrypoint.sh docker/prod_entrypoint.sh ./docker/
|
||||
COPY litellm/ ./litellm/
|
||||
COPY pyproject.toml README.md schema.prisma poetry.lock ./
|
||||
|
||||
# Copy pre-built wheels and install everything at once
|
||||
COPY --from=builder /wheels/ /wheels/
|
||||
COPY --from=builder /app/dist/*.whl .
|
||||
|
||||
# Install all dependencies in one step with no-cache for smaller image
|
||||
RUN pip install --no-cache-dir *.whl /wheels/* --no-index --find-links=/wheels/ && \
|
||||
rm -f *.whl && \
|
||||
rm -rf /wheels
|
||||
|
||||
# SECURITY FIX: nodejs-wheel-binaries (pip package used by Prisma) bundles a complete
|
||||
# npm with old vulnerable deps at /usr/lib/python3.*/site-packages/nodejs_wheel/.
|
||||
# Patch every copy of tar, glob, and brace-expansion inside that tree.
|
||||
RUN GLOBAL="$(npm root -g)" && \
|
||||
[ -n "$GLOBAL" ] || { echo "ERROR: npm root -g returned empty; aborting"; exit 1; } && \
|
||||
find /usr/lib -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "glob" -path "*/node_modules/glob" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/glob" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "brace-expansion" -path "*/node_modules/@isaacs/brace-expansion" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/@isaacs/brace-expansion" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "minimatch" -path "*/node_modules/minimatch" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/minimatch" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "diff" -path "*/node_modules/diff" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/diff" "$d"; \
|
||||
done
|
||||
|
||||
# Generate prisma client and set permissions
|
||||
# Convert Windows line endings to Unix for entrypoint scripts
|
||||
RUN prisma generate && \
|
||||
sed -i 's/\r$//' docker/entrypoint.sh && \
|
||||
sed -i 's/\r$//' docker/prod_entrypoint.sh && \
|
||||
chmod +x docker/entrypoint.sh && \
|
||||
chmod +x docker/prod_entrypoint.sh
|
||||
COPY --from=builder /app /app
|
||||
|
||||
EXPOSE 4000/tcp
|
||||
|
||||
ENTRYPOINT ["docker/prod_entrypoint.sh"]
|
||||
|
||||
# Append "--detailed_debug" to the end of CMD to view detailed debug logs
|
||||
CMD ["--port", "4000"]
|
||||
CMD ["--port", "4000"]
|
||||
|
|
|
|||
|
|
@ -1,16 +1,30 @@
|
|||
FROM python:3.11-slim
|
||||
ARG UV_IMAGE=ghcr.io/astral-sh/uv:0.10.9@sha256:10902f58a1606787602f303954cea099626a4adb02acbac4c69920fe9d278f82
|
||||
FROM $UV_IMAGE AS uvbin
|
||||
|
||||
FROM python:3.13-slim@sha256:739e7213785e88c0f702dcdc12c0973afcbd606dbf021a589cab77d6b00b579d
|
||||
|
||||
WORKDIR /app
|
||||
|
||||
# Copy health check script and requirements
|
||||
# Copy the uv binary and the health check script.
|
||||
COPY --from=uvbin /uv /usr/local/bin/uv
|
||||
COPY pyproject.toml uv.lock /app/
|
||||
COPY scripts/health_check/health_check_client.py /app/health_check_client.py
|
||||
COPY scripts/health_check/health_check_requirements.txt /app/requirements.txt
|
||||
|
||||
# Install dependencies
|
||||
RUN pip install --no-cache-dir -r requirements.txt
|
||||
# Resolve and install the health-check dependencies from the project lockfile
|
||||
# so the runtime image stays self-contained and reproducible.
|
||||
RUN uv export --frozen --no-default-groups --only-group healthcheck --no-emit-project --no-hashes --output-file /tmp/health-check-requirements.txt \
|
||||
&& uv pip install --system -r /tmp/health-check-requirements.txt \
|
||||
&& rm /tmp/health-check-requirements.txt \
|
||||
&& rm /app/pyproject.toml /app/uv.lock \
|
||||
&& chmod +x /app/health_check_client.py
|
||||
|
||||
# Make script executable
|
||||
RUN chmod +x /app/health_check_client.py
|
||||
# Run as non-root user
|
||||
RUN groupadd --gid 1000 appuser && useradd --uid 1000 --gid 1000 --no-create-home appuser
|
||||
USER appuser
|
||||
|
||||
# Health check
|
||||
HEALTHCHECK --interval=30s --timeout=5s --start-period=5s --retries=3 \
|
||||
CMD ["python", "/app/health_check_client.py", "--help"]
|
||||
|
||||
# Set entrypoint
|
||||
ENTRYPOINT ["python", "/app/health_check_client.py"]
|
||||
|
|
|
|||
|
|
@ -1,56 +1,66 @@
|
|||
# Base images
|
||||
ARG LITELLM_BUILD_IMAGE=cgr.dev/chainguard/wolfi-base
|
||||
ARG LITELLM_RUNTIME_IMAGE=cgr.dev/chainguard/wolfi-base
|
||||
ARG LITELLM_BUILD_IMAGE=cgr.dev/chainguard/wolfi-base@sha256:a5a619c1793039dcf92f02178f37c94bb3d6001403716da59d6092dfe8d9b502
|
||||
ARG LITELLM_RUNTIME_IMAGE=cgr.dev/chainguard/wolfi-base@sha256:a5a619c1793039dcf92f02178f37c94bb3d6001403716da59d6092dfe8d9b502
|
||||
ARG PROXY_EXTRAS_SOURCE=published
|
||||
ARG UV_IMAGE=ghcr.io/astral-sh/uv:0.10.9@sha256:10902f58a1606787602f303954cea099626a4adb02acbac4c69920fe9d278f82
|
||||
|
||||
FROM $UV_IMAGE AS uvbin
|
||||
|
||||
# -----------------
|
||||
# Builder Stage
|
||||
# -----------------
|
||||
FROM $LITELLM_BUILD_IMAGE AS builder
|
||||
ARG PROXY_EXTRAS_SOURCE
|
||||
WORKDIR /app
|
||||
USER root
|
||||
|
||||
# Install build dependencies with retry logic (includes node for UI build)
|
||||
COPY --from=uvbin /uv /usr/local/bin/uv
|
||||
COPY --from=uvbin /uvx /usr/local/bin/uvx
|
||||
|
||||
RUN for i in 1 2 3; do \
|
||||
apk add --no-cache \
|
||||
python3 \
|
||||
python3-dev \
|
||||
py3-pip \
|
||||
clang \
|
||||
llvm \
|
||||
lld \
|
||||
gcc \
|
||||
linux-headers \
|
||||
build-base \
|
||||
bash \
|
||||
nodejs \
|
||||
npm && break || sleep 5; \
|
||||
done \
|
||||
&& pip install --no-cache-dir --upgrade pip build
|
||||
apk add --no-cache \
|
||||
python3 \
|
||||
python3-dev \
|
||||
gcc \
|
||||
bash \
|
||||
coreutils \
|
||||
curl \
|
||||
openssl \
|
||||
libsndfile \
|
||||
nodejs && break || sleep 5; \
|
||||
done
|
||||
|
||||
# Cache Python dependencies
|
||||
COPY requirements.txt .
|
||||
RUN pip wheel --no-cache-dir --wheel-dir=/wheels/ -r requirements.txt \
|
||||
&& pip wheel --no-cache-dir --wheel-dir=/wheels/ "semantic_router==0.1.11" "aurelio-sdk==0.0.19" "PyJWT==2.12.0"
|
||||
ENV UV_PROJECT_ENVIRONMENT=/app/.venv \
|
||||
UV_LINK_MODE=copy \
|
||||
PATH="/app/.venv/bin:${PATH}" \
|
||||
LITELLM_NON_ROOT=true \
|
||||
PRISMA_BINARY_CACHE_DIR=/app/.cache/prisma-python/binaries \
|
||||
PRISMA_CLI_BINARY_TARGETS="debian-openssl-3.0.x" \
|
||||
XDG_CACHE_HOME=/app/.cache
|
||||
|
||||
# Copy source after dependency layers
|
||||
# Copy dependency metadata first for layer caching
|
||||
COPY pyproject.toml uv.lock ./
|
||||
COPY enterprise/pyproject.toml enterprise/
|
||||
COPY litellm-proxy-extras/pyproject.toml litellm-proxy-extras/
|
||||
|
||||
# Install third-party dependencies (cached unless pyproject.toml/uv.lock change)
|
||||
RUN --mount=type=cache,target=/app/.cache/uv,id=litellm-uv-cache \
|
||||
uv sync --frozen --no-install-project --no-install-workspace --no-default-groups --no-editable \
|
||||
--extra proxy \
|
||||
--extra proxy-runtime \
|
||||
--extra extra_proxy \
|
||||
--extra semantic-router \
|
||||
--python python3
|
||||
|
||||
# Copy full source tree
|
||||
COPY . .
|
||||
|
||||
# Set non-root flag for build time consistency
|
||||
ENV LITELLM_NON_ROOT=true
|
||||
|
||||
# Build Admin UI using the upstream command order while keeping a single RUN layer
|
||||
RUN mkdir -p /var/lib/litellm/ui && \
|
||||
npm install -g npm@latest && npm cache clean --force && \
|
||||
cd /app/ui/litellm-dashboard && \
|
||||
if [ -f "/app/enterprise/enterprise_ui/enterprise_colors.json" ]; then \
|
||||
cp /app/enterprise/enterprise_ui/enterprise_colors.json ./ui_colors.json; \
|
||||
fi && \
|
||||
npm install --legacy-peer-deps && \
|
||||
npm run build && \
|
||||
cp -r /app/ui/litellm-dashboard/out/* /var/lib/litellm/ui/ && \
|
||||
mkdir -p /var/lib/litellm/assets && \
|
||||
# Stage the pre-built Admin UI from the checked-in Next.js static export.
|
||||
# _experimental/out/ is regenerated as part of the release runbook.
|
||||
# Restructure extensionless routes (foo.html -> foo/index.html) to match the layout
|
||||
# proxy_server.py expects, and drop a readiness marker.
|
||||
RUN mkdir -p /var/lib/litellm/ui /var/lib/litellm/assets && \
|
||||
cp -r /app/litellm/proxy/_experimental/out/. /var/lib/litellm/ui/ && \
|
||||
cp /app/litellm/proxy/logo.jpg /var/lib/litellm/assets/logo.jpg && \
|
||||
( cd /var/lib/litellm/ui && \
|
||||
for html_file in *.html; do \
|
||||
|
|
@ -60,175 +70,79 @@ RUN mkdir -p /var/lib/litellm/ui && \
|
|||
mv "$html_file" "$folder_name/index.html"; \
|
||||
fi; \
|
||||
done && \
|
||||
touch .litellm_ui_ready ) && \
|
||||
cd /app/ui/litellm-dashboard && rm -rf ./out
|
||||
touch .litellm_ui_ready )
|
||||
|
||||
# Build litellm wheel and place it in wheels dir (replace any PyPI wheels)
|
||||
RUN rm -rf dist/* && python -m build && \
|
||||
rm -f /wheels/litellm-*.whl && \
|
||||
cp dist/*.whl /wheels/
|
||||
|
||||
# Optionally build local litellm-proxy-extras wheel
|
||||
RUN if [ "$PROXY_EXTRAS_SOURCE" = "local" ]; then \
|
||||
cd /app/litellm-proxy-extras && rm -rf dist && python -m build && \
|
||||
cp dist/*.whl /wheels/; \
|
||||
RUN --mount=type=cache,target=/app/.cache/uv,id=litellm-uv-cache \
|
||||
if [ "$PROXY_EXTRAS_SOURCE" = "published" ]; then \
|
||||
uv sync --frozen --no-default-groups --no-editable \
|
||||
--extra proxy \
|
||||
--extra proxy-runtime \
|
||||
--extra extra_proxy \
|
||||
--extra semantic-router \
|
||||
--python python3 \
|
||||
--no-sources-package litellm-proxy-extras; \
|
||||
else \
|
||||
uv sync --frozen --no-default-groups --no-editable \
|
||||
--extra proxy \
|
||||
--extra proxy-runtime \
|
||||
--extra extra_proxy \
|
||||
--extra semantic-router \
|
||||
--python python3; \
|
||||
fi
|
||||
|
||||
# Pre-cache Prisma binaries in the builder stage
|
||||
ENV PRISMA_BINARY_CACHE_DIR=/app/.cache/prisma-python/binaries \
|
||||
PRISMA_CLI_BINARY_TARGETS="debian-openssl-3.0.x" \
|
||||
XDG_CACHE_HOME=/app/.cache \
|
||||
PATH="/usr/lib/python3.13/site-packages/nodejs/bin:${PATH}"
|
||||
RUN prisma generate --schema=./schema.prisma
|
||||
|
||||
RUN pip install --no-cache-dir prisma==0.11.0 nodejs-wheel-binaries==24.13.1 \
|
||||
&& mkdir -p /app/.cache/npm
|
||||
RUN sed -i 's/\r$//' docker/entrypoint.sh && chmod +x docker/entrypoint.sh && \
|
||||
sed -i 's/\r$//' docker/prod_entrypoint.sh && chmod +x docker/prod_entrypoint.sh
|
||||
|
||||
RUN NPM_CONFIG_CACHE=/app/.cache/npm \
|
||||
python -c "import prisma.cli.prisma as p; p.ensure_cached()"
|
||||
|
||||
RUN prisma generate && \
|
||||
prisma --version && \
|
||||
prisma migrate diff --from-empty --to-schema-datamodel ./schema.prisma --script > /dev/null 2>&1 || true
|
||||
|
||||
# -----------------
|
||||
# Runtime Stage
|
||||
# -----------------
|
||||
FROM $LITELLM_RUNTIME_IMAGE AS runtime
|
||||
ARG PROXY_EXTRAS_SOURCE
|
||||
WORKDIR /app
|
||||
USER root
|
||||
|
||||
# Install runtime dependencies with retry
|
||||
RUN for i in 1 2 3; do \
|
||||
apk upgrade --no-cache && break || sleep 5; \
|
||||
done \
|
||||
&& for i in 1 2 3; do \
|
||||
apk add --no-cache python3 py3-pip bash openssl tzdata nodejs npm supervisor && break || sleep 5; \
|
||||
done \
|
||||
&& apk upgrade --no-cache nodejs \
|
||||
&& npm install -g npm@latest tar@7.5.11 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 \
|
||||
&& GLOBAL="$(npm root -g)" \
|
||||
&& find "$GLOBAL/npm" -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
done \
|
||||
&& find "$GLOBAL/npm" -type d -name "glob" -path "*/node_modules/glob" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/glob" "$d"; \
|
||||
done \
|
||||
&& find "$GLOBAL/npm" -type d -name "brace-expansion" -path "*/node_modules/@isaacs/brace-expansion" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/@isaacs/brace-expansion" "$d"; \
|
||||
done \
|
||||
&& find "$GLOBAL/npm" -type d -name "minimatch" -path "*/node_modules/minimatch" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/minimatch" "$d"; \
|
||||
done \
|
||||
&& find "$GLOBAL/npm" -type d -name "diff" -path "*/node_modules/diff" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/diff" "$d"; \
|
||||
done \
|
||||
&& find /usr/local/lib /usr/lib -path "*/node_modules/npm/package.json" -exec \
|
||||
sed -i 's/"tar": "\^7\.5\.[0-9]*"/"tar": "^7.5.10"/g; s/"minimatch": "\^10\.[0-9.]*"/"minimatch": "^10.2.4"/g' {} + 2>/dev/null \
|
||||
&& npm cache clean --force \
|
||||
&& { apk del --no-cache npm 2>/dev/null || true; }
|
||||
apk upgrade --no-cache && break || sleep 5; \
|
||||
done && \
|
||||
for i in 1 2 3; do \
|
||||
apk add --no-cache python3 bash openssl tzdata supervisor libsndfile nodejs && break || sleep 5; \
|
||||
done
|
||||
|
||||
# Copy artifacts from builder
|
||||
COPY --from=builder /app/requirements.txt /app/requirements.txt
|
||||
COPY --from=builder /app/docker/entrypoint.sh /app/docker/prod_entrypoint.sh /app/docker/
|
||||
COPY --from=builder /app/docker/supervisord.conf /etc/supervisord.conf
|
||||
COPY --from=builder /app/schema.prisma /app/
|
||||
# Copy prisma_migration.py for Helm migrations job compatibility
|
||||
COPY --from=builder /app/litellm/proxy/prisma_migration.py /app/litellm/proxy/prisma_migration.py
|
||||
COPY --from=builder /wheels/ /wheels/
|
||||
COPY --from=builder /app /app
|
||||
COPY --from=builder /var/lib/litellm/ui /var/lib/litellm/ui
|
||||
COPY --from=builder /var/lib/litellm/assets /var/lib/litellm/assets
|
||||
COPY --from=builder /app/.cache /app/.cache
|
||||
COPY --from=builder /app/litellm-proxy-extras /app/litellm-proxy-extras
|
||||
COPY --from=builder \
|
||||
/usr/lib/python3.13/site-packages/nodejs* \
|
||||
/usr/lib/python3.13/site-packages/prisma* \
|
||||
/usr/lib/python3.13/site-packages/tomlkit* \
|
||||
/usr/lib/python3.13/site-packages/nodeenv* \
|
||||
/usr/lib/python3.13/site-packages/
|
||||
COPY --from=builder /usr/bin/prisma /usr/bin/prisma
|
||||
COPY --from=builder /app/docker/supervisord.conf /etc/supervisord.conf
|
||||
|
||||
# Final runtime environment configuration
|
||||
ENV PRISMA_BINARY_CACHE_DIR=/app/.cache/prisma-python/binaries \
|
||||
ENV PATH="/app/.venv/bin:${PATH}" \
|
||||
PRISMA_BINARY_CACHE_DIR=/app/.cache/prisma-python/binaries \
|
||||
PRISMA_CLI_BINARY_TARGETS="debian-openssl-3.0.x" \
|
||||
HOME=/app \
|
||||
LITELLM_NON_ROOT=true \
|
||||
XDG_CACHE_HOME=/app/.cache
|
||||
|
||||
# Install packages from wheels and optional extras without network
|
||||
RUN pip install --no-index --find-links=/wheels/ -r requirements.txt && \
|
||||
pip install --no-index --find-links=/wheels/ /wheels/litellm-*-py3-none-any.whl && \
|
||||
pip install --no-index --find-links=/wheels/ --no-deps semantic_router==0.1.11 && \
|
||||
pip install --no-index --find-links=/wheels/ aurelio-sdk==0.0.19 && \
|
||||
if [ "$PROXY_EXTRAS_SOURCE" = "local" ]; then \
|
||||
if ls /wheels/litellm_proxy_extras-*.whl >/dev/null 2>&1; then \
|
||||
pip install --no-index --find-links=/wheels/ /wheels/litellm_proxy_extras-*.whl; \
|
||||
else \
|
||||
echo "litellm_proxy_extras wheel not found; skipping local install"; \
|
||||
fi; \
|
||||
fi
|
||||
|
||||
# SECURITY FIX: nodejs-wheel-binaries (pip package used by Prisma) bundles a complete
|
||||
# npm with old vulnerable deps at /usr/lib/python3.*/site-packages/nodejs_wheel/.
|
||||
# Patch every copy of tar, glob, and brace-expansion inside that tree.
|
||||
RUN GLOBAL="$(npm root -g)" && \
|
||||
[ -n "$GLOBAL" ] || { echo "ERROR: npm root -g returned empty; aborting"; exit 1; } && \
|
||||
find /usr/lib -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "glob" -path "*/node_modules/glob" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/glob" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "brace-expansion" -path "*/node_modules/@isaacs/brace-expansion" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/@isaacs/brace-expansion" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "minimatch" -path "*/node_modules/minimatch" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/minimatch" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -type d -name "diff" -path "*/node_modules/diff" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/diff" "$d"; \
|
||||
done
|
||||
|
||||
# Permissions, cleanup, and Prisma prep
|
||||
# Convert Windows line endings to Unix for entrypoint scripts
|
||||
RUN sed -i 's/\r$//' docker/entrypoint.sh && \
|
||||
sed -i 's/\r$//' docker/prod_entrypoint.sh && \
|
||||
chmod +x docker/entrypoint.sh docker/prod_entrypoint.sh && \
|
||||
mkdir -p /nonexistent /.npm /var/lib/litellm/assets /var/lib/litellm/ui && \
|
||||
chown -R nobody:nogroup /app /var/lib/litellm/ui /var/lib/litellm/assets /nonexistent /.npm && \
|
||||
pip uninstall jwt -y || true && \
|
||||
pip uninstall PyJWT -y || true && \
|
||||
pip install --no-index --find-links=/wheels/ PyJWT==2.12.0 --no-cache-dir && \
|
||||
rm -rf /wheels && \
|
||||
PRISMA_PATH=$(python -c "import os, prisma; print(os.path.dirname(prisma.__file__))") && \
|
||||
chown -R nobody:nogroup $PRISMA_PATH && \
|
||||
LITELLM_PKG_MIGRATIONS_PATH="$(python -c 'import os, litellm_proxy_extras; print(os.path.dirname(litellm_proxy_extras.__file__))' 2>/dev/null || echo '')/migrations" && \
|
||||
[ -n "$LITELLM_PKG_MIGRATIONS_PATH" ] && chown -R nobody:nogroup $LITELLM_PKG_MIGRATIONS_PATH && \
|
||||
LITELLM_PROXY_EXTRAS_PATH=$(python -c "import os, litellm_proxy_extras; print(os.path.dirname(litellm_proxy_extras.__file__))" 2>/dev/null || echo "") && \
|
||||
chgrp -R 0 $PRISMA_PATH /var/lib/litellm/ui /var/lib/litellm/assets && \
|
||||
[ -n "$LITELLM_PROXY_EXTRAS_PATH" ] && chgrp -R 0 $LITELLM_PROXY_EXTRAS_PATH || true && \
|
||||
chmod -R g=u $PRISMA_PATH /var/lib/litellm/ui /var/lib/litellm/assets && \
|
||||
[ -n "$LITELLM_PROXY_EXTRAS_PATH" ] && chmod -R g=u $LITELLM_PROXY_EXTRAS_PATH || true && \
|
||||
chmod -R g+w $PRISMA_PATH /var/lib/litellm/ui /var/lib/litellm/assets && \
|
||||
[ -n "$LITELLM_PROXY_EXTRAS_PATH" ] && chmod -R g+w $LITELLM_PROXY_EXTRAS_PATH || true && \
|
||||
chmod -R g+rX $PRISMA_PATH && \
|
||||
chmod -R g+rX /app/.cache && \
|
||||
mkdir -p /tmp/.npm /nonexistent /.npm
|
||||
|
||||
# Switch to non-root user for runtime
|
||||
USER nobody
|
||||
|
||||
# Generate Prisma client as nobody user to ensure correct file ownership
|
||||
RUN prisma generate
|
||||
|
||||
# Prisma runtime knobs for offline containers
|
||||
ENV PRISMA_SKIP_POSTINSTALL_GENERATE=1 \
|
||||
XDG_CACHE_HOME=/app/.cache \
|
||||
PRISMA_SKIP_POSTINSTALL_GENERATE=1 \
|
||||
PRISMA_HIDE_UPDATE_MESSAGE=1 \
|
||||
PRISMA_ENGINES_CHECKSUM_IGNORE_MISSING=1 \
|
||||
NPM_CONFIG_CACHE=/app/.cache/npm \
|
||||
NPM_CONFIG_PREFER_OFFLINE=true \
|
||||
PRISMA_OFFLINE_MODE=true
|
||||
|
||||
RUN mkdir -p /nonexistent /var/lib/litellm/assets /var/lib/litellm/ui && \
|
||||
chown -R nobody:nogroup /app /var/lib/litellm/ui /var/lib/litellm/assets /nonexistent && \
|
||||
PRISMA_PATH=$(python -c "import os, prisma; print(os.path.dirname(prisma.__file__))") && \
|
||||
chown -R nobody:nogroup "$PRISMA_PATH" && \
|
||||
LITELLM_PKG_MIGRATIONS_PATH="$(python -c 'import os, litellm_proxy_extras; print(os.path.dirname(litellm_proxy_extras.__file__))' 2>/dev/null || echo '')/migrations" && \
|
||||
[ -n "$LITELLM_PKG_MIGRATIONS_PATH" ] && chown -R nobody:nogroup "$LITELLM_PKG_MIGRATIONS_PATH" || true && \
|
||||
LITELLM_PROXY_EXTRAS_PATH=$(python -c "import os, litellm_proxy_extras; print(os.path.dirname(litellm_proxy_extras.__file__))" 2>/dev/null || echo "") && \
|
||||
chgrp -R 0 "$PRISMA_PATH" /var/lib/litellm/ui /var/lib/litellm/assets && \
|
||||
[ -n "$LITELLM_PROXY_EXTRAS_PATH" ] && chgrp -R 0 "$LITELLM_PROXY_EXTRAS_PATH" || true && \
|
||||
chmod -R g=u "$PRISMA_PATH" /var/lib/litellm/ui /var/lib/litellm/assets && \
|
||||
[ -n "$LITELLM_PROXY_EXTRAS_PATH" ] && chmod -R g=u "$LITELLM_PROXY_EXTRAS_PATH" || true && \
|
||||
chmod -R g+w "$PRISMA_PATH" /var/lib/litellm/ui /var/lib/litellm/assets && \
|
||||
[ -n "$LITELLM_PROXY_EXTRAS_PATH" ] && chmod -R g+w "$LITELLM_PROXY_EXTRAS_PATH" || true && \
|
||||
chmod -R g+rX "$PRISMA_PATH" /var/lib/litellm/ui /var/lib/litellm/assets /app/.cache
|
||||
|
||||
USER 65534
|
||||
|
||||
RUN prisma generate --schema=./schema.prisma
|
||||
|
||||
EXPOSE 4000/tcp
|
||||
|
||||
ENTRYPOINT ["/app/docker/prod_entrypoint.sh"]
|
||||
CMD ["--port", "4000"]
|
||||
|
|
|
|||
|
|
@ -13,19 +13,19 @@ To build and run the application, you will use the `docker-compose.yml` file loc
|
|||
|
||||
### 1. Set the Master Key
|
||||
|
||||
The application requires a `MASTER_KEY` for signing and validating tokens. You must set this key as an environment variable before running the application.
|
||||
The application requires a `LITELLM_MASTER_KEY` for signing and validating tokens. You must set this key as an environment variable before running the application.
|
||||
|
||||
Create a `.env` file in the root of the project and add the following line:
|
||||
|
||||
```
|
||||
MASTER_KEY=your-secret-key
|
||||
LITELLM_MASTER_KEY=your-secret-key
|
||||
```
|
||||
|
||||
Replace `your-secret-key` with a strong, randomly generated secret.
|
||||
|
||||
### 2. Build and Run the Containers
|
||||
|
||||
Once you have set the `MASTER_KEY`, you can build and run the containers using the following command:
|
||||
Once you have set the `LITELLM_MASTER_KEY`, you can build and run the containers using the following command:
|
||||
|
||||
```bash
|
||||
docker compose up -d --build
|
||||
|
|
@ -89,4 +89,4 @@ This command should succeed (showing engine versions) even with `--network none`
|
|||
## Troubleshooting
|
||||
|
||||
- **`build_admin_ui.sh: not found`**: This error can occur if the Docker build context is not set correctly. Ensure that you are running the `docker-compose` command from the root of the project.
|
||||
- **`Master key is not initialized`**: This error means the `MASTER_key` environment variable is not set. Make sure you have created a `.env` file in the project root with the `MASTER_KEY` defined.
|
||||
- **`Master key is not initialized`**: This error means the `LITELLM_MASTER_KEY` environment variable is not set. Make sure you have created a `.env` file in the project root with the `LITELLM_MASTER_KEY` defined.
|
||||
|
|
|
|||
|
|
@ -1,31 +1,55 @@
|
|||
FROM python:3.13-alpine
|
||||
ARG UV_IMAGE=ghcr.io/astral-sh/uv:0.10.9@sha256:10902f58a1606787602f303954cea099626a4adb02acbac4c69920fe9d278f82
|
||||
FROM $UV_IMAGE AS uvbin
|
||||
|
||||
FROM python:3.13-slim@sha256:739e7213785e88c0f702dcdc12c0973afcbd606dbf021a589cab77d6b00b579d
|
||||
|
||||
ARG LITELLM_VERSION=1.83.0
|
||||
|
||||
WORKDIR /app
|
||||
|
||||
ENV HOME=/home/litellm
|
||||
ENV PATH="${HOME}/venv/bin:$PATH"
|
||||
COPY --from=uvbin /uv /usr/local/bin/uv
|
||||
COPY --from=uvbin /uvx /usr/local/bin/uvx
|
||||
|
||||
# Install runtime dependencies
|
||||
# Note: Using Python 3.13 for compatibility with ddtrace and other packages
|
||||
# rust and cargo are required for building ddtrace from source
|
||||
# musl-dev and libffi-dev are needed for some Python packages on Alpine
|
||||
RUN apk update && \
|
||||
apk add --no-cache gcc musl-dev libffi-dev openssl openssl-dev rust cargo
|
||||
RUN apt-get update && \
|
||||
apt-get install -y --no-install-recommends gcc libffi-dev nodejs npm && \
|
||||
rm -rf /var/lib/apt/lists/*
|
||||
|
||||
RUN python -m venv ${HOME}/venv
|
||||
RUN ${HOME}/venv/bin/pip install --no-cache-dir --upgrade pip
|
||||
ENV UV_PROJECT_ENVIRONMENT=/app/.venv \
|
||||
UV_LINK_MODE=copy \
|
||||
PATH="/app/.venv/bin:${PATH}"
|
||||
|
||||
COPY docker/build_from_pip/requirements.txt .
|
||||
RUN --mount=type=cache,target=${HOME}/.cache/pip \
|
||||
${HOME}/venv/bin/pip install -r requirements.txt
|
||||
|
||||
# Copy Prisma schema file
|
||||
COPY schema.prisma .
|
||||
|
||||
# Generate prisma client
|
||||
RUN prisma generate
|
||||
# This image is specifically for validating/installing the published PyPI
|
||||
# artifact, not the checked-out source tree.
|
||||
# Keep the moved proxy-runtime packages explicit until the published PyPI
|
||||
# artifact includes that extra; newer releases will simply dedupe these.
|
||||
RUN uv venv --python python && \
|
||||
uv pip install --python /app/.venv/bin/python \
|
||||
"litellm[proxy,proxy-runtime]==${LITELLM_VERSION}" \
|
||||
"google-cloud-aiplatform==1.133.0" \
|
||||
"google-genai==1.37.0" \
|
||||
"anthropic[vertex]==0.84.0" \
|
||||
"grpcio==1.78.0" \
|
||||
"prometheus-client==0.20.0" \
|
||||
"langfuse==2.59.7" \
|
||||
"opentelemetry-api==1.28.0" \
|
||||
"opentelemetry-sdk==1.28.0" \
|
||||
"opentelemetry-exporter-otlp==1.28.0" \
|
||||
"ddtrace==2.19.0" \
|
||||
"sentry-sdk==2.21.0" \
|
||||
"mangum==0.17.0" \
|
||||
"azure-ai-contentsafety==1.0.0" \
|
||||
"azure-storage-file-datalake==12.20.0" \
|
||||
"pypdf==6.7.5" \
|
||||
"llm-sandbox==0.3.31" \
|
||||
"detect-secrets==1.5.0" \
|
||||
"prisma==0.11.0" \
|
||||
"openai==2.24.0"
|
||||
|
||||
RUN prisma generate --schema=./schema.prisma
|
||||
|
||||
EXPOSE 4000/tcp
|
||||
|
||||
ENTRYPOINT ["litellm"]
|
||||
CMD ["--port", "4000"]
|
||||
CMD ["--port", "4000"]
|
||||
|
|
|
|||
|
|
@ -1,6 +0,0 @@
|
|||
litellm[proxy]==1.67.4.dev1 # Specify the litellm version you want to use
|
||||
prometheus_client
|
||||
langfuse
|
||||
prisma
|
||||
openai==1.99.9
|
||||
ddtrace==2.19.0 # for advanced DD tracing / profiling
|
||||
|
|
@ -1,13 +1,16 @@
|
|||
#!/bin/bash
|
||||
echo $(pwd)
|
||||
set -euo pipefail
|
||||
|
||||
# Run the Python migration script
|
||||
python3 litellm/proxy/prisma_migration.py
|
||||
REPO_ROOT="$(cd -- "$(dirname -- "${BASH_SOURCE[0]}")/.." && pwd)"
|
||||
VENV_PYTHON="$REPO_ROOT/.venv/bin/python"
|
||||
MIGRATION_SCRIPT="$REPO_ROOT/litellm/proxy/prisma_migration.py"
|
||||
|
||||
# Check if the Python script executed successfully
|
||||
if [ $? -eq 0 ]; then
|
||||
echo "Migration script ran successfully!"
|
||||
if [ -x "$VENV_PYTHON" ]; then
|
||||
"$VENV_PYTHON" "$MIGRATION_SCRIPT"
|
||||
elif command -v uv >/dev/null 2>&1; then
|
||||
(cd "$REPO_ROOT" && uv run --no-sync python "$MIGRATION_SCRIPT")
|
||||
else
|
||||
echo "Migration script failed!"
|
||||
exit 1
|
||||
python3 "$MIGRATION_SCRIPT"
|
||||
fi
|
||||
|
||||
echo "Migration script ran successfully!"
|
||||
|
|
|
|||
|
|
@ -1,3 +1,4 @@
|
|||
#!/bin/bash
|
||||
pip install semantic_router==0.1.11 --no-deps
|
||||
pip install aurelio-sdk==0.0.19
|
||||
set -euo pipefail
|
||||
|
||||
# semantic-router dependencies are installed via `uv sync`.
|
||||
|
|
|
|||
|
|
@ -2,7 +2,7 @@ schemaVersion: 2.0.0
|
|||
|
||||
metadataTest:
|
||||
entrypoint: ["docker/prod_entrypoint.sh"]
|
||||
user: "nobody"
|
||||
user: "65534"
|
||||
workdir: "/app"
|
||||
|
||||
fileExistenceTests:
|
||||
|
|
|
|||
23
docs/my-website/.gitignore
vendored
23
docs/my-website/.gitignore
vendored
|
|
@ -1,23 +0,0 @@
|
|||
# Dependencies
|
||||
/node_modules
|
||||
|
||||
# Production
|
||||
/build
|
||||
|
||||
# Generated files
|
||||
.docusaurus
|
||||
.cache-loader
|
||||
|
||||
# Misc
|
||||
.DS_Store
|
||||
.env
|
||||
.env.local
|
||||
.env.development.local
|
||||
.env.test.local
|
||||
.env.production.local
|
||||
|
||||
npm-debug.log*
|
||||
yarn-debug.log*
|
||||
yarn-error.log*
|
||||
yarn.lock
|
||||
pnpm-lock.yaml
|
||||
|
|
@ -1,9 +0,0 @@
|
|||
FROM python:3.14.0a3-slim
|
||||
|
||||
COPY . /app
|
||||
WORKDIR /app
|
||||
RUN pip install -r requirements.txt
|
||||
|
||||
EXPOSE $PORT
|
||||
|
||||
CMD litellm --host 0.0.0.0 --port $PORT --workers 10 --config config.yaml
|
||||
|
|
@ -1,41 +0,0 @@
|
|||
# Website
|
||||
|
||||
This website is built using [Docusaurus 2](https://docusaurus.io/), a modern static website generator.
|
||||
|
||||
### Installation
|
||||
|
||||
```
|
||||
$ yarn
|
||||
```
|
||||
|
||||
### Local Development
|
||||
|
||||
```
|
||||
$ yarn start
|
||||
```
|
||||
|
||||
This command starts a local development server and opens up a browser window. Most changes are reflected live without having to restart the server.
|
||||
|
||||
### Build
|
||||
|
||||
```
|
||||
$ yarn build
|
||||
```
|
||||
|
||||
This command generates static content into the `build` directory and can be served using any static contents hosting service.
|
||||
|
||||
### Deployment
|
||||
|
||||
Using SSH:
|
||||
|
||||
```
|
||||
$ USE_SSH=true yarn deploy
|
||||
```
|
||||
|
||||
Not using SSH:
|
||||
|
||||
```
|
||||
$ GIT_USER=<Your GitHub username> yarn deploy
|
||||
```
|
||||
|
||||
If you are using GitHub pages for hosting, this command is a convenient way to build the website and push to the `gh-pages` branch.
|
||||
|
|
@ -1,3 +0,0 @@
|
|||
module.exports = {
|
||||
presets: [require.resolve('@docusaurus/core/lib/babel/preset')],
|
||||
};
|
||||
File diff suppressed because it is too large
Load diff
|
|
@ -1,138 +0,0 @@
|
|||
---
|
||||
slug: anthropic-wildcard-model-access-incident
|
||||
title: "Incident Report: Wildcard Blocking New Models After Cost Map Reload"
|
||||
date: 2026-02-23T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
- krrish
|
||||
- ishaan-alt
|
||||
tags: [incident-report, proxy, auth, model-access]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
**Date:** Feb 23, 2026
|
||||
**Duration:** ~3 hours
|
||||
**Severity:** High (for users with provider wildcard access rules)
|
||||
**Status:** Resolved
|
||||
|
||||
## Summary
|
||||
|
||||
When a new Anthropic model (e.g. `claude-sonnet-4-6`) was added to the LiteLLM model cost map and a cost map reload was triggered, requests to the new model were rejected with:
|
||||
|
||||
```
|
||||
key not allowed to access model. This key can only access models=['anthropic/*']. Tried to access claude-sonnet-4-6.
|
||||
```
|
||||
|
||||
The reload updated `litellm.model_cost` correctly but never re-ran `add_known_models()`, so `litellm.anthropic_models` (the in-memory set used by the wildcard resolver) remained stale. The new model was invisible to the `anthropic/*` wildcard even though the cost map knew about it.
|
||||
|
||||
- **LLM calls:** All requests to newly-added Anthropic models were blocked with a 401.
|
||||
- **Existing models:** Unaffected — only models missing from the stale provider set were impacted.
|
||||
- **Other providers:** Same bug class existed for any provider wildcard (e.g. `openai/*`, `gemini/*`).
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
---
|
||||
|
||||
## Background
|
||||
|
||||
LiteLLM supports provider-level wildcard access rules. When an admin configures a key or team with `models=['anthropic/*']`, any model whose provider resolves to `anthropic` should be allowed. The resolution happens in `_model_custom_llm_provider_matches_wildcard_pattern`:
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
A["1. Request arrives for claude-sonnet-4-6"] --> B["2. Auth check: can this key call this model?
|
||||
proxy/auth/auth_checks.py"]
|
||||
B --> C["3. Key has models=['anthropic/*']
|
||||
→ wildcard match attempted"]
|
||||
C --> D["4. get_llm_provider('claude-sonnet-4-6')
|
||||
checks litellm.anthropic_models set"]
|
||||
D -->|"model IN set"| E["5a. ✅ Provider = 'anthropic'
|
||||
→ 'anthropic/claude-sonnet-4-6' matches 'anthropic/*'"]
|
||||
D -->|"model NOT IN set"| F["5b. ❌ Provider unknown
|
||||
→ exception raised → wildcard returns False"]
|
||||
E --> G["6. Request allowed"]
|
||||
F --> H["6. 401: key not allowed to access model"]
|
||||
|
||||
style E fill:#d4edda,stroke:#28a745
|
||||
style F fill:#f8d7da,stroke:#dc3545
|
||||
style H fill:#f8d7da,stroke:#dc3545
|
||||
style D fill:#fff3cd,stroke:#ffc107
|
||||
```
|
||||
|
||||
`litellm.anthropic_models` is a Python `set` populated at import time by `add_known_models()`. It is the source `get_llm_provider()` consults to map a bare model name like `claude-sonnet-4-6` to the provider string `"anthropic"`.
|
||||
|
||||
---
|
||||
|
||||
## Root Cause
|
||||
|
||||
`add_known_models()` is called **once** at module import time. Both reload paths in `proxy_server.py` updated `litellm.model_cost` with the fresh map but never called `add_known_models()` again:
|
||||
|
||||
```python
|
||||
# Before the fix — both reload paths looked like this:
|
||||
new_model_cost_map = get_model_cost_map(url=model_cost_map_url)
|
||||
litellm.model_cost = new_model_cost_map # ✅ cost map updated
|
||||
_invalidate_model_cost_lowercase_map() # ✅ cache cleared
|
||||
# ❌ add_known_models() never called
|
||||
# → litellm.anthropic_models still has the old set
|
||||
# → new model not in the set
|
||||
# → get_llm_provider() raises for the new model
|
||||
# → wildcard match returns False
|
||||
# → 401 for every request to the new model
|
||||
```
|
||||
|
||||
The gap existed in two places:
|
||||
1. `_check_and_reload_model_cost_map` — the periodic automatic reload (every 10 s)
|
||||
2. The `/reload/model_cost_map` admin endpoint — the manual reload
|
||||
|
||||
**Timeline:**
|
||||
|
||||
1. New model (`claude-sonnet-4-6`) added to `model_prices_and_context_window.json`
|
||||
2. Admin triggers cost map reload via UI → `litellm.model_cost` updated
|
||||
3. Users with `anthropic/*` wildcard keys attempt requests to `claude-sonnet-4-6`
|
||||
4. `get_llm_provider('claude-sonnet-4-6')` raises → wildcard returns False → 401
|
||||
5. Admin reloads cost map again — same result (root cause not addressed)
|
||||
6. ~3 hours of investigation → root cause identified → fix deployed
|
||||
|
||||
---
|
||||
|
||||
## The Fix
|
||||
|
||||
After each reload, `add_known_models()` is called with the freshly fetched map passed explicitly. Passing the map directly (rather than relying on the module-level reference) removes any ambiguity about which dict is iterated:
|
||||
|
||||
```python
|
||||
# After the fix — both reload paths now do:
|
||||
new_model_cost_map = get_model_cost_map(url=model_cost_map_url)
|
||||
litellm.model_cost = new_model_cost_map
|
||||
_invalidate_model_cost_lowercase_map()
|
||||
litellm.add_known_models(model_cost_map=new_model_cost_map) # ✅ sets repopulated
|
||||
```
|
||||
|
||||
`add_known_models()` was also updated to accept an optional explicit map so callers cannot accidentally iterate a stale module-level reference:
|
||||
|
||||
```python
|
||||
# Before
|
||||
def add_known_models():
|
||||
for key, value in model_cost.items(): # reads module global — ambiguous after reload
|
||||
...
|
||||
|
||||
# After
|
||||
def add_known_models(model_cost_map: Optional[Dict] = None):
|
||||
_map = model_cost_map if model_cost_map is not None else model_cost
|
||||
for key, value in _map.items(): # always iterates the map you just fetched
|
||||
...
|
||||
```
|
||||
|
||||
After the fix, the provider sets (`anthropic_models`, `open_ai_chat_completion_models`, etc.) are always consistent with `litellm.model_cost` immediately after every reload. New models become accessible via wildcard rules without any proxy restart.
|
||||
|
||||
---
|
||||
|
||||
## Remediation
|
||||
|
||||
| # | Action | Status | Code |
|
||||
|---|---|---|---|
|
||||
| 1 | Call `add_known_models(model_cost_map=...)` in the periodic reload path | ✅ Done | [`proxy_server.py#L4393`](https://github.com/BerriAI/litellm/blob/main/litellm/proxy/proxy_server.py#L4393) |
|
||||
| 2 | Call `add_known_models(model_cost_map=...)` in the `/reload/model_cost_map` endpoint | ✅ Done | [`proxy_server.py#L11904`](https://github.com/BerriAI/litellm/blob/main/litellm/proxy/proxy_server.py#L11904) |
|
||||
| 3 | Update `add_known_models()` to accept an explicit map parameter | ✅ Done | [`__init__.py#L617`](https://github.com/BerriAI/litellm/blob/main/litellm/__init__.py#L617) |
|
||||
| 4 | Regression test: `add_known_models(model_cost_map=...)` populates provider sets | ✅ Done | [`test_auth_checks.py`](https://github.com/BerriAI/litellm/blob/main/tests/proxy_unit_tests/test_auth_checks.py) |
|
||||
| 5 | Regression test: `anthropic/*` wildcard grants/denies access correctly after reload | ✅ Done | [`test_auth_checks.py`](https://github.com/BerriAI/litellm/blob/main/tests/proxy_unit_tests/test_auth_checks.py) |
|
||||
|
||||
---
|
||||
|
|
@ -1,48 +0,0 @@
|
|||
litellm:
|
||||
name: LiteLLM Team
|
||||
title: LiteLLM Core Team
|
||||
url: https://github.com/BerriAI/litellm
|
||||
image_url: https://github.com/BerriAI.png
|
||||
|
||||
sameer:
|
||||
name: Sameer Kankute
|
||||
title: SWE @ LiteLLM (LLM Translation)
|
||||
url: https://www.linkedin.com/in/sameer-kankute/
|
||||
image_url: https://pbs.twimg.com/profile_images/2001352686994907136/ONgNuSk5_400x400.jpg
|
||||
|
||||
krrish:
|
||||
name: Krrish Dholakia
|
||||
title: CEO, LiteLLM
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
|
||||
ishaan:
|
||||
name: Ishaan Jaffer
|
||||
title: CTO, LiteLLM
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
|
||||
# Alias for typo in name
|
||||
ishaan-alt:
|
||||
name: Ishaan Jaff
|
||||
title: CTO, LiteLLM
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
|
||||
ryan:
|
||||
name: Ryan Crabbe
|
||||
title: Performance Engineer, LiteLLM
|
||||
url: https://www.linkedin.com/in/ryan-crabbe-0b9687214
|
||||
image_url: https://media.licdn.com/dms/image/v2/D5603AQHt1t9Z4BJ6Gw/profile-displayphoto-shrink_400_400/profile-displayphoto-shrink_400_400/0/1724453682340?e=1772064000&v=beta&t=VXdmr13rsNB05wyA2F1TENOB5UuDHUZ0FCHTolNyR5M
|
||||
|
||||
alexsander:
|
||||
name: Alexsander Hamir
|
||||
title: Performance Engineer, LiteLLM
|
||||
url: https://www.linkedin.com/in/alexsander-baptista/
|
||||
image_url: https://github.com/AlexsanderHamir.png
|
||||
|
||||
yuneng:
|
||||
name: Yuneng Jiang
|
||||
title: SWE @ LiteLLM (Full Stack)
|
||||
url: https://www.linkedin.com/in/yuneng-david-jiang-455676139/
|
||||
image_url: https://avatars.githubusercontent.com/u/171294688?v=4
|
||||
|
|
@ -1,168 +0,0 @@
|
|||
---
|
||||
slug: claude-code-beta-headers-incident
|
||||
title: "Incident Report: Invalid beta headers with Claude Code"
|
||||
date: 2026-02-16T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
- ishaan-alt
|
||||
- krrish
|
||||
tags: [incident-report, anthropic, stability]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
**Date:** February 13, 2026
|
||||
**Duration:** ~3 hours
|
||||
**Severity:** High
|
||||
**Status:** Resolved
|
||||
|
||||
> **Note:** This fix will be available starting from `v1.81.13-nightly` or higher of LiteLLM.
|
||||
|
||||
## Summary
|
||||
|
||||
Claude Code began sending unsupported Anthropic beta headers to non-Anthropic providers (Bedrock, Azure AI, Vertex AI), causing `invalid beta flag` errors. LiteLLM was forwarding all beta headers without provider-specific validation. Users experienced request failures when routing Claude Code requests through LiteLLM to these providers.
|
||||
|
||||
- **LLM calls to Anthropic:** No impact.
|
||||
- **LLM calls to Bedrock/Azure/Vertex:** Failed with `invalid beta flag` errors when unsupported headers were present.
|
||||
- **Cost tracking and routing:** No impact.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
---
|
||||
|
||||
## Background
|
||||
|
||||
Anthropic uses beta headers to enable experimental features in Claude. When Claude Code makes API requests, it includes headers like `anthropic-beta: prompt-caching-scope-2026-01-05,advanced-tool-use-2025-11-20`. However, not all providers support all Anthropic beta features.
|
||||
|
||||
Before this incident, LiteLLM forwarded all beta headers to all providers without validation:
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant CC as Claude Code
|
||||
participant LP as LiteLLM (old behavior)
|
||||
participant Provider as Provider (Bedrock/Azure/Vertex)
|
||||
|
||||
CC->>LP: Request with beta headers
|
||||
Note over CC,LP: anthropic-beta: header1,header2,header3
|
||||
|
||||
LP->>Provider: Forward ALL headers (no validation)
|
||||
Note over LP,Provider: anthropic-beta: header1,header2,header3
|
||||
|
||||
Provider-->>LP: ❌ Error: invalid beta flag
|
||||
LP-->>CC: Request fails
|
||||
```
|
||||
|
||||
Requests succeeded for Anthropic (native support) but failed for other providers when Claude Code sent headers those providers didn't support.
|
||||
|
||||
---
|
||||
|
||||
## Root cause
|
||||
|
||||
LiteLLM lacked provider-specific beta header validation. When Claude Code introduced new beta features or sent headers that specific providers didn't support, those headers were blindly forwarded, causing provider API errors.
|
||||
|
||||
---
|
||||
|
||||
## Remediation
|
||||
|
||||
| # | Action | Status | Code |
|
||||
|---|---|---|---|
|
||||
| 1 | Create `anthropic_beta_headers_config.json` with provider-specific mappings | ✅ Done | [`anthropic_beta_headers_config.json`](https://github.com/BerriAI/litellm/blob/main/litellm/anthropic_beta_headers_config.json) |
|
||||
| 2 | Implement strict validation: headers must be explicitly mapped to be forwarded | ✅ Done | [`litellm_logging.py`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm_core_utils/litellm_logging.py) |
|
||||
| 3 | Add `/reload/anthropic_beta_headers` endpoint for dynamic config updates | ✅ Done | Proxy management endpoints |
|
||||
| 4 | Add `/schedule/anthropic_beta_headers_reload` for automatic periodic updates | ✅ Done | Proxy management endpoints |
|
||||
| 5 | Support `LITELLM_ANTHROPIC_BETA_HEADERS_URL` for custom config sources | ✅ Done | Environment configuration |
|
||||
| 6 | Support `LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS` for air-gapped deployments | ✅ Done | Environment configuration |
|
||||
|
||||
Now LiteLLM validates and transforms headers per-provider:
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant CC as Claude Code
|
||||
participant LP as LiteLLM (new behavior)
|
||||
participant Config as Beta Headers Config
|
||||
participant Provider as Provider (Bedrock/Azure/Vertex)
|
||||
|
||||
CC->>LP: Request with beta headers
|
||||
Note over CC,LP: anthropic-beta: header1,header2,header3
|
||||
|
||||
LP->>Config: Load header mapping for provider
|
||||
Config-->>LP: Returns mapping (header→value or null)
|
||||
|
||||
Note over LP: Validate & Transform:<br/>1. Check if header exists in mapping<br/>2. Filter out null values<br/>3. Map to provider-specific names
|
||||
|
||||
LP->>Provider: Request with filtered & mapped headers
|
||||
Note over LP,Provider: anthropic-beta: mapped-header2<br/>(header1, header3 filtered out)
|
||||
|
||||
Provider-->>LP: ✅ Success response
|
||||
LP-->>CC: Response
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Dynamic configuration updates
|
||||
|
||||
A key improvement is zero-downtime configuration updates. When Anthropic releases new beta features, users can update their configuration without restarting:
|
||||
|
||||
```bash
|
||||
# Manually trigger reload (no restart needed)
|
||||
curl -X POST "https://your-proxy-url/reload/anthropic_beta_headers" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
|
||||
# Or schedule automatic reloads every 24 hours
|
||||
curl -X POST "https://your-proxy-url/schedule/anthropic_beta_headers_reload?hours=24" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
This prevents future incidents where Claude Code introduces new headers before LiteLLM configuration is updated.
|
||||
|
||||
---
|
||||
|
||||
## Configuration format
|
||||
|
||||
The `anthropic_beta_headers_config.json` file maps input headers to provider-specific output headers:
|
||||
|
||||
```json
|
||||
{
|
||||
"description": "Mapping of Anthropic beta headers for each provider.",
|
||||
"anthropic": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"computer-use-2025-01-24": "computer-use-2025-01-24"
|
||||
},
|
||||
"bedrock_converse": {
|
||||
"advanced-tool-use-2025-11-20": null,
|
||||
"computer-use-2025-01-24": "computer-use-2025-01-24"
|
||||
},
|
||||
"azure_ai": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"computer-use-2025-01-24": "computer-use-2025-01-24"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Validation rules:**
|
||||
1. Headers must exist in the mapping for the target provider
|
||||
2. Headers with `null` values are filtered out (unsupported)
|
||||
3. Header names can be transformed per-provider (e.g., Bedrock uses different names for some features)
|
||||
|
||||
---
|
||||
|
||||
## Resolution steps for users
|
||||
|
||||
For users still experiencing issues, update to the latest LiteLLM version if < v1.81.11-nightly:
|
||||
|
||||
```bash
|
||||
pip install --upgrade litellm
|
||||
```
|
||||
|
||||
Or manually reload the configuration without restarting:
|
||||
|
||||
```bash
|
||||
curl -X POST "https://your-proxy-url/reload/anthropic_beta_headers" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Related documentation
|
||||
|
||||
- [Managing Anthropic Beta Headers](../../docs/proxy/sync_anthropic_beta_headers) - Complete configuration guide
|
||||
- [`anthropic_beta_headers_config.json`](https://github.com/BerriAI/litellm/blob/main/litellm/anthropic_beta_headers_config.json) - Current configuration file
|
||||
|
|
@ -1,723 +0,0 @@
|
|||
---
|
||||
slug: claude_opus_4_6
|
||||
title: "Day 0 Support: Claude Opus 4.6"
|
||||
date: 2026-02-05T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
- ishaan-alt
|
||||
- krrish
|
||||
description: "Day 0 support for Claude Opus 4.6 on LiteLLM AI Gateway - use across Anthropic, Azure, Vertex AI, and Bedrock."
|
||||
tags: [anthropic, claude, opus 4.6]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
LiteLLM now supports Claude Opus 4.6 on Day 0. Use it across Anthropic, Azure, Vertex AI, and Bedrock through the LiteLLM AI Gateway.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
## Docker Image
|
||||
|
||||
```bash
|
||||
docker pull ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6
|
||||
```
|
||||
|
||||
## Usage - Anthropic
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-6
|
||||
litellm_params:
|
||||
model: anthropic/claude-opus-4-6
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e ANTHROPIC_API_KEY=$ANTHROPIC_API_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Azure
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-6
|
||||
litellm_params:
|
||||
model: azure_ai/claude-opus-4-6
|
||||
api_key: os.environ/AZURE_AI_API_KEY
|
||||
api_base: os.environ/AZURE_AI_API_BASE # https://<resource>.services.ai.azure.com
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e AZURE_AI_API_KEY=$AZURE_AI_API_KEY \
|
||||
-e AZURE_AI_API_BASE=$AZURE_AI_API_BASE \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Vertex AI
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-6
|
||||
litellm_params:
|
||||
model: vertex_ai/claude-opus-4-6
|
||||
vertex_project: os.environ/VERTEX_PROJECT
|
||||
vertex_location: us-east5
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e VERTEX_PROJECT=$VERTEX_PROJECT \
|
||||
-e GOOGLE_APPLICATION_CREDENTIALS=/app/credentials.json \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
-v $(pwd)/credentials.json:/app/credentials.json \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Bedrock
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-6
|
||||
litellm_params:
|
||||
model: bedrock/anthropic.claude-opus-4-6-v1
|
||||
aws_access_key_id: os.environ/AWS_ACCESS_KEY_ID
|
||||
aws_secret_access_key: os.environ/AWS_SECRET_ACCESS_KEY
|
||||
aws_region_name: us-east-1
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e AWS_ACCESS_KEY_ID=$AWS_ACCESS_KEY_ID \
|
||||
-e AWS_SECRET_ACCESS_KEY=$AWS_SECRET_ACCESS_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Advanced Features
|
||||
|
||||
### Compaction
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="completions" label="/chat/completions">
|
||||
|
||||
Litellm supports enabling compaction for the new claude-opus-4-6.
|
||||
|
||||
**Enabling Compaction**
|
||||
|
||||
To enable compaction, add the `context_management` parameter with the `compact_20260112` edit type:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What is the weather in San Francisco?"
|
||||
}
|
||||
],
|
||||
"context_management": {
|
||||
"edits": [
|
||||
{
|
||||
"type": "compact_20260112"
|
||||
}
|
||||
]
|
||||
},
|
||||
"max_tokens": 100
|
||||
}'
|
||||
```
|
||||
All the parameters supported for context_management by anthropic are supported and can be directly added. Litellm automatically adds the `compact-2026-01-12` beta header in the request.
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="messages" label="/v1/messages">
|
||||
|
||||
Enable compaction to reduce context size while preserving key information. LiteLLM automatically adds the `compact-2026-01-12` beta header when compaction is enabled.
|
||||
|
||||
:::info
|
||||
**Provider Support:** Compaction is supported on Anthropic, Azure AI, and Vertex AI. It is **not supported** on Bedrock (Invoke or Converse APIs).
|
||||
:::
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'x-api-key: sk-12345' \
|
||||
--header 'content-type: application/json' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"max_tokens": 4096,
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Hi"
|
||||
}
|
||||
],
|
||||
"context_management": {
|
||||
"edits": [
|
||||
{
|
||||
"type": "compact_20260112"
|
||||
}
|
||||
]
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
||||
**Response with Compaction Block**
|
||||
|
||||
The response will include the compaction summary in `provider_specific_fields.compaction_blocks`:
|
||||
|
||||
```json
|
||||
{
|
||||
"id": "chatcmpl-a6c105a3-4b25-419e-9551-c800633b6cb2",
|
||||
"created": 1770357619,
|
||||
"model": "claude-opus-4-6",
|
||||
"object": "chat.completion",
|
||||
"choices": [
|
||||
{
|
||||
"finish_reason": "length",
|
||||
"index": 0,
|
||||
"message": {
|
||||
"content": "I don't have access to real-time data, so I can't provide the current weather in San Francisco. To get up-to-date weather information, I'd recommend checking:\n\n- **Weather websites** like weather.com, accuweather.com, or wunderground.com\n- **Search engines** – just Google \"San Francisco weather\"\n- **Weather apps** on your phone (e.g., Apple Weather, Google Weather)\n- **National",
|
||||
"role": "assistant",
|
||||
"provider_specific_fields": {
|
||||
"compaction_blocks": [
|
||||
{
|
||||
"type": "compaction",
|
||||
"content": "Summary of the conversation: The user requested help building a web scraper..."
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
],
|
||||
"usage": {
|
||||
"completion_tokens": 100,
|
||||
"prompt_tokens": 86,
|
||||
"total_tokens": 186
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Using Compaction Blocks in Follow-up Requests**
|
||||
|
||||
To continue the conversation with compaction, include the compaction block in the assistant message's `provider_specific_fields`:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "How can I build a web scraper?"
|
||||
},
|
||||
{
|
||||
"role": "assistant",
|
||||
"content": [
|
||||
{
|
||||
"type": "text",
|
||||
"text": "Certainly! To build a basic web scraper, you'll typically use a programming language like Python along with libraries such as `requests` (for fetching web pages) and `BeautifulSoup` (for parsing HTML). Here's a basic example:\n\n```python\nimport requests\nfrom bs4 import BeautifulSoup\n\nurl = 'https://example.com'\nresponse = requests.get(url)\nsoup = BeautifulSoup(response.text, 'html.parser')\n\n# Extract and print all text\ntext = soup.get_text()\nprint(text)\n```\n\nLet me know what you're interested in scraping or if you need help with a specific website!"
|
||||
}
|
||||
],
|
||||
"provider_specific_fields": {
|
||||
"compaction_blocks": [
|
||||
{
|
||||
"type": "compaction",
|
||||
"content": "Summary of the conversation: The user asked how to build a web scraper, and the assistant gave an overview using Python with requests and BeautifulSoup."
|
||||
}
|
||||
]
|
||||
}
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"content": "How do I use it to scrape product prices?"
|
||||
}
|
||||
],
|
||||
"context_management": {
|
||||
"edits": [
|
||||
{
|
||||
"type": "compact_20260112"
|
||||
}
|
||||
]
|
||||
},
|
||||
"max_tokens": 100
|
||||
}'
|
||||
```
|
||||
|
||||
**Streaming Support**
|
||||
|
||||
Compaction blocks are also supported in streaming mode. You'll receive:
|
||||
- `compaction_start` event when a compaction block begins
|
||||
- `compaction_delta` events with the compaction content
|
||||
- The accumulated `compaction_blocks` in `provider_specific_fields`
|
||||
|
||||
### Adaptive Thinking
|
||||
|
||||
:::note
|
||||
When using `reasoning_effort` with Claude Opus 4.6, all values (`low`, `medium`, `high`) are mapped to `thinking: {type: "adaptive"}`. To use explicit thinking budgets with `type: "enabled"`, pass the native `thinking` parameter directly (see "Native thinking param" tab below).
|
||||
:::
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="completions" label="/chat/completions">
|
||||
|
||||
LiteLLM supports adaptive thinking through the `reasoning_effort` parameter:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Solve this complex problem: What is the optimal strategy for..."
|
||||
}
|
||||
],
|
||||
"reasoning_effort": "high"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="messages" label="/v1/messages">
|
||||
|
||||
Use the `thinking` parameter with `type: "adaptive"` to enable adaptive thinking mode:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'x-api-key: sk-12345' \
|
||||
--header 'content-type: application/json' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"max_tokens": 16000,
|
||||
"thinking": {
|
||||
"type": "adaptive"
|
||||
},
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Explain why the sum of two even numbers is always even."
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="native" label="Native thinking param">
|
||||
|
||||
Use the `thinking` parameter directly for adaptive thinking via the SDK:
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-opus-4-6",
|
||||
messages=[{"role": "user", "content": "Solve this complex problem: What is the optimal strategy for..."}],
|
||||
thinking={"type": "adaptive"},
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Effort Levels
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="completions" label="/chat/completions">
|
||||
|
||||
Four effort levels available: `low`, `medium`, `high` (default), and `max`. Pass directly via the `output_config` parameter:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Explain quantum computing"
|
||||
}
|
||||
],
|
||||
"output_config": {
|
||||
"effort": "medium"
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
You can use reasoning effort plus output_config to have more control on the model.
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="messages" label="/v1/messages">
|
||||
|
||||
Four effort levels available: `low`, `medium`, `high` (default), and `max`. Pass directly via the `output_config` parameter:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'x-api-key: sk-12345' \
|
||||
--header 'content-type: application/json' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"max_tokens": 4096,
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Explain quantum computing"
|
||||
}
|
||||
],
|
||||
"output_config": {
|
||||
"effort": "medium"
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### 1M Token Context (Beta)
|
||||
|
||||
Opus 4.6 supports 1M token context. Premium pricing applies for prompts exceeding 200k tokens ($10/$37.50 per million input/output tokens). LiteLLM supports cost calculations for 1M token contexts.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="completions" label="/chat/completions">
|
||||
|
||||
To use the 1M token context window, you need to forward the `anthropic-beta` header from your client to the LLM provider.
|
||||
|
||||
**Step 1: Enable header forwarding in your config**
|
||||
|
||||
```yaml
|
||||
general_settings:
|
||||
forward_client_headers_to_llm_api: true
|
||||
```
|
||||
|
||||
**Step 2: Send requests with the beta header**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--header 'anthropic-beta: context-1m-2025-08-07' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Analyze this large document..."
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="messages" label="/v1/messages">
|
||||
|
||||
To use the 1M token context window, you need to forward the `anthropic-beta` header from your client to the LLM provider.
|
||||
|
||||
**Step 1: Enable header forwarding in your config**
|
||||
|
||||
```yaml
|
||||
general_settings:
|
||||
forward_client_headers_to_llm_api: true
|
||||
```
|
||||
|
||||
**Step 2: Send requests with the beta header**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'x-api-key: sk-12345' \
|
||||
--header 'anthropic-beta: context-1m-2025-08-07' \
|
||||
--header 'content-type: application/json' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"max_tokens": 16000,
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Analyze this large document..."
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
:::tip
|
||||
You can combine multiple beta headers by separating them with commas:
|
||||
```bash
|
||||
--header 'anthropic-beta: context-1m-2025-08-07,compact-2026-01-12'
|
||||
```
|
||||
:::
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### US-Only Inference
|
||||
|
||||
Available at 1.1× token pricing. LiteLLM automatically tracks costs for US-only inference.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="completions" label="/chat/completions">
|
||||
|
||||
Use the `inference_geo` parameter to specify US-only inference:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What is the capital of France?"
|
||||
}
|
||||
],
|
||||
"inference_geo": "us"
|
||||
}'
|
||||
```
|
||||
|
||||
LiteLLM will automatically apply the 1.1× pricing multiplier for US-only inference in cost tracking.
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="messages" label="/v1/messages">
|
||||
|
||||
Use the `inference_geo` parameter to specify US-only inference:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'x-api-key: sk-12345' \
|
||||
--header 'content-type: application/json' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"max_tokens": 4096,
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What is the capital of France?"
|
||||
}
|
||||
],
|
||||
"inference_geo": "us"
|
||||
}'
|
||||
```
|
||||
|
||||
LiteLLM will automatically apply the 1.1× pricing multiplier for US-only inference in cost tracking.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Fast Mode
|
||||
|
||||
:::info
|
||||
Fast mode is **only supported on the Anthropic provider** (`anthropic/claude-opus-4-6`). It is not available on Azure AI, Vertex AI, or Bedrock.
|
||||
:::
|
||||
|
||||
**Pricing:**
|
||||
- Standard: $5 input / $25 output per MTok
|
||||
- Fast: $30 input / $150 output per MTok (6× premium)
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="completions" label="/chat/completions">
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Refactor this module..."
|
||||
}
|
||||
],
|
||||
"max_tokens": 4096,
|
||||
"speed": "fast"
|
||||
}'
|
||||
```
|
||||
|
||||
**Using OpenAI SDK:**
|
||||
|
||||
```python
|
||||
import openai
|
||||
|
||||
client = openai.OpenAI(
|
||||
api_key="your-litellm-key",
|
||||
base_url="http://0.0.0.0:4000"
|
||||
)
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="claude-opus-4-6",
|
||||
messages=[{"role": "user", "content": "Refactor this module..."}],
|
||||
max_tokens=4096,
|
||||
extra_body={"speed": "fast"}
|
||||
)
|
||||
```
|
||||
|
||||
**Using LiteLLM SDK:**
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="anthropic/claude-opus-4-6",
|
||||
messages=[{"role": "user", "content": "Refactor this module..."}],
|
||||
max_tokens=4096,
|
||||
speed="fast"
|
||||
)
|
||||
```
|
||||
|
||||
LiteLLM automatically tracks the higher costs for fast mode in usage and cost calculations.
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="messages" label="/v1/messages">
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'x-api-key: sk-12345' \
|
||||
--header 'content-type: application/json' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"max_tokens": 4096,
|
||||
"speed": "fast",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Refactor this module..."
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
LiteLLM automatically:
|
||||
- Adds the `fast-mode-2026-02-01` beta header
|
||||
- Tracks the 6× premium pricing in cost calculations
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
|
@ -1,279 +0,0 @@
|
|||
---
|
||||
slug: claude_sonnet_4_6
|
||||
title: "Day 0 Support: Claude Sonnet 4.6"
|
||||
date: 2026-02-17T10:00:00
|
||||
authors:
|
||||
- ishaan-alt
|
||||
- krrish
|
||||
description: "Day 0 support for Claude Sonnet 4.6 on LiteLLM AI Gateway - use across Anthropic, Azure, Vertex AI, and Bedrock."
|
||||
tags: [anthropic, claude, sonnet 4.6]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
LiteLLM now supports Claude Sonnet 4.6 on Day 0. Use it across Anthropic, Azure, Vertex AI, and Bedrock through the LiteLLM AI Gateway.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
## Docker Image
|
||||
|
||||
```bash
|
||||
docker pull ghcr.io/berriai/litellm:v1.81.3-stable.sonnet-4-6
|
||||
```
|
||||
|
||||
## Usage - Anthropic
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-sonnet-4-6
|
||||
litellm_params:
|
||||
model: anthropic/claude-sonnet-4-6
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e ANTHROPIC_API_KEY=$ANTHROPIC_API_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:v1.81.3-stable.sonnet-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-sonnet-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="sdk" label="LiteLLM SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="anthropic/claude-sonnet-4-6",
|
||||
messages=[{"role": "user", "content": "what llm are you"}]
|
||||
)
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Azure
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-sonnet-4-6
|
||||
litellm_params:
|
||||
model: azure_ai/claude-sonnet-4-6
|
||||
api_key: os.environ/AZURE_AI_API_KEY
|
||||
api_base: os.environ/AZURE_AI_API_BASE # https://<resource>.services.ai.azure.com
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e AZURE_AI_API_KEY=$AZURE_AI_API_KEY \
|
||||
-e AZURE_AI_API_BASE=$AZURE_AI_API_BASE \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:v1.81.3-stable.sonnet-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-sonnet-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="sdk" label="LiteLLM SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="azure_ai/claude-sonnet-4-6",
|
||||
api_key="your-azure-api-key",
|
||||
api_base="https://<resource>.services.ai.azure.com",
|
||||
messages=[{"role": "user", "content": "what llm are you"}]
|
||||
)
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Vertex AI
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-sonnet-4-6
|
||||
litellm_params:
|
||||
model: vertex_ai/claude-sonnet-4-6
|
||||
vertex_project: os.environ/VERTEX_PROJECT
|
||||
vertex_location: us-east5
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e VERTEX_PROJECT=$VERTEX_PROJECT \
|
||||
-e GOOGLE_APPLICATION_CREDENTIALS=/app/credentials.json \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
-v $(pwd)/credentials.json:/app/credentials.json \
|
||||
ghcr.io/berriai/litellm:v1.81.3-stable.sonnet-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-sonnet-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="sdk" label="LiteLLM SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="vertex_ai/claude-sonnet-4-6",
|
||||
vertex_project="your-project-id",
|
||||
vertex_location="us-east5",
|
||||
messages=[{"role": "user", "content": "what llm are you"}]
|
||||
)
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Bedrock
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-sonnet-4-6
|
||||
litellm_params:
|
||||
model: bedrock/anthropic.claude-sonnet-4-6-v1
|
||||
aws_access_key_id: os.environ/AWS_ACCESS_KEY_ID
|
||||
aws_secret_access_key: os.environ/AWS_SECRET_ACCESS_KEY
|
||||
aws_region_name: us-east-1
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e AWS_ACCESS_KEY_ID=$AWS_ACCESS_KEY_ID \
|
||||
-e AWS_SECRET_ACCESS_KEY=$AWS_SECRET_ACCESS_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:v1.81.3-stable.sonnet-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-sonnet-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="sdk" label="LiteLLM SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="bedrock/anthropic.claude-sonnet-4-6-v1",
|
||||
aws_access_key_id="your-access-key",
|
||||
aws_secret_access_key="your-secret-key",
|
||||
aws_region_name="us-east-1",
|
||||
messages=[{"role": "user", "content": "what llm are you"}]
|
||||
)
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
|
@ -1,211 +0,0 @@
|
|||
---
|
||||
slug: fastapi-middleware-performance
|
||||
title: "Your Middleware Could Be a Bottleneck"
|
||||
date: 2026-02-07T10:00:00
|
||||
authors:
|
||||
- krrish
|
||||
- ishaan-alt
|
||||
- ryan
|
||||
description: "How we improved LiteLLM proxy latency and throughput by replacing a single middleware base class"
|
||||
tags: [performance, fastapi, middleware]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import { BaseHTTPMiddlewareAnimation, PureASGIAnimation, BenchmarkVisualization } from '@site/src/components/MiddlewareDiagrams';
|
||||
|
||||
> How we improved LiteLLM proxy latency and throughput by replacing a single, simple middleware base class
|
||||
|
||||
---
|
||||
|
||||
## Our Setup
|
||||
|
||||
The LiteLLM proxy server has two middleware layers. The first is Starlette's `CORSMiddleware` (re-exported by FastAPI), which is a pure ASGI middleware. Then we have a simple BaseHTTPMiddleware called PrometheusAuthMiddleware.
|
||||
|
||||
The job of `PrometheusAuthMiddleware` is to authenticate requests to the `/metrics` endpoint. It's not on by default, you enable it with a flag in your proxy config:
|
||||
|
||||
<details>
|
||||
<summary>Proxy config flag</summary>
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
require_auth_for_metrics_endpoint: true
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
The middleware checks two things: is the request hitting `/metrics`, and is auth even enabled? If both checks fail, which they do for the vast majority of requests, it just passes the request through unchanged.
|
||||
|
||||
<details>
|
||||
<summary>PrometheusAuthMiddleware source</summary>
|
||||
|
||||
```python
|
||||
class PrometheusAuthMiddleware(BaseHTTPMiddleware):
|
||||
async def dispatch(self, request: Request, call_next):
|
||||
if self._is_prometheus_metrics_endpoint(request):
|
||||
if self._should_run_auth_on_metrics_endpoint() is True:
|
||||
try:
|
||||
await user_api_key_auth(request=request, api_key=...)
|
||||
except Exception as e:
|
||||
return JSONResponse(status_code=401, content=...)
|
||||
response = await call_next(request)
|
||||
return response
|
||||
|
||||
@staticmethod
|
||||
def _is_prometheus_metrics_endpoint(request: Request):
|
||||
if "/metrics" in request.url.path:
|
||||
return True
|
||||
return False
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
Looks harmless. Subclass `BaseHTTPMiddleware`, implement `dispatch()`, done. This is what you will see in Starlette's documentation<sup>[1](#footnote-1)</sup>.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
---
|
||||
|
||||
## What BaseHTTPMiddleware Actually Does
|
||||
|
||||
When you write a `dispatch()` method, you'd expect the request to flow straight through your function and out the other side. What actually happens is much more involved.
|
||||
|
||||
On every request, even a pure passthrough (meaning nothing happens), `BaseHTTPMiddleware` creates **7 intermediate objects and tasks**:
|
||||
|
||||
<BaseHTTPMiddlewareAnimation />
|
||||
|
||||
It wraps the request in a new object to track body state, creates a synchronization event, allocates an in-memory channel to pass messages between your middleware and the inner app, sets up a task group to manage the lifecycle, and then runs your actual route handler in a *separate background task* when you call `call_next()`. The response body then flows back through that in-memory channel, gets re-wrapped in a streaming response object, and finally reaches the caller. That's a lot.
|
||||
|
||||
For a middleware that for us, does nothing on 99.9% of requests, paying this cost doesn't make sense.
|
||||
|
||||
Compare that to a pure ASGI middleware, which we can have just check the request path and continue along.
|
||||
|
||||
<PureASGIAnimation />
|
||||
|
||||
Our middleware is doing something really simple. For the vast majority of requests it doesn't need to do anything at all but just let the request pass through. It doesn't need task groups, memory streams, or cancel scopes. It needs a function call.
|
||||
|
||||
---
|
||||
|
||||
## Comparing Both
|
||||
|
||||
We replaced the `BaseHTTPMiddleware` subclass with a pure ASGI middleware. To benchmark the difference, we used Apache Bench<sup>[2](#footnote-2)</sup> to compare both configurations of LiteLLM's middleware stack: the old setup (1 pure ASGI + 1 `BaseHTTPMiddleware`) against the new setup (2 pure ASGI).
|
||||
|
||||
A minimal FastAPI app serves `GET /health` → `PlainTextResponse("ok")`. The endpoint does zero work to isolate the middleware overhead: any difference between configs is purely the cost of the middleware plumbing itself. Both middlewares are just calling the next layer. Same work, different base class.
|
||||
|
||||
Apache Bench (`ab`) fires requests at the server with 1,000 concurrent connections and a single uvicorn worker. One worker means one event loop, so the benchmark directly measures how each middleware design handles concurrent load on a single thread.
|
||||
|
||||
<BenchmarkVisualization />
|
||||
|
||||
<details>
|
||||
<summary>Try it yourself</summary>
|
||||
|
||||
Save the script below as `benchmark_middleware.py`, then run:
|
||||
|
||||
```bash
|
||||
# Terminal 1 — start the "before" server (1 ASGI + 1 BaseHTTPMiddleware)
|
||||
python benchmark_middleware.py --middleware mixed
|
||||
|
||||
# Terminal 2 — benchmark it
|
||||
ab -n 50000 -c 1000 http://localhost:8000/health
|
||||
|
||||
# Stop the server, then start the "after" server (2x pure ASGI)
|
||||
python benchmark_middleware.py --middleware asgi
|
||||
|
||||
# Terminal 2 — benchmark again
|
||||
ab -n 50000 -c 1000 http://localhost:8000/health
|
||||
```
|
||||
|
||||
```python
|
||||
import argparse
|
||||
import uvicorn
|
||||
from fastapi import FastAPI
|
||||
from fastapi.responses import PlainTextResponse
|
||||
from starlette.middleware.base import BaseHTTPMiddleware
|
||||
from starlette.requests import Request
|
||||
from starlette.types import ASGIApp, Receive, Scope, Send
|
||||
|
||||
|
||||
class NoOpBaseHTTPMiddleware(BaseHTTPMiddleware):
|
||||
async def dispatch(self, request: Request, call_next):
|
||||
return await call_next(request)
|
||||
|
||||
|
||||
class NoOpPureASGIMiddleware:
|
||||
def __init__(self, app: ASGIApp) -> None:
|
||||
self.app = app
|
||||
|
||||
async def __call__(self, scope: Scope, receive: Receive, send: Send) -> None:
|
||||
await self.app(scope, receive, send)
|
||||
|
||||
|
||||
def create_app(middleware_type: str | None = None, layers: int = 2) -> FastAPI:
|
||||
app = FastAPI()
|
||||
|
||||
@app.get("/health")
|
||||
async def health():
|
||||
return PlainTextResponse("ok")
|
||||
|
||||
if middleware_type == "mixed":
|
||||
app.add_middleware(NoOpBaseHTTPMiddleware)
|
||||
app.add_middleware(NoOpPureASGIMiddleware)
|
||||
elif middleware_type == "asgi":
|
||||
for _ in range(layers):
|
||||
app.add_middleware(NoOpPureASGIMiddleware)
|
||||
|
||||
return app
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--middleware", choices=["asgi", "mixed"], default=None)
|
||||
parser.add_argument("--layers", type=int, default=2)
|
||||
parser.add_argument("--port", type=int, default=8000)
|
||||
args = parser.parse_args()
|
||||
|
||||
app = create_app(middleware_type=args.middleware, layers=args.layers)
|
||||
uvicorn.run(app, host="0.0.0.0", port=args.port, workers=1, log_level="warning")
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## Our Change
|
||||
|
||||
Here's what we replaced it with:
|
||||
|
||||
```python
|
||||
class PrometheusAuthMiddleware:
|
||||
def __init__(self, app: ASGIApp) -> None:
|
||||
self.app = app
|
||||
|
||||
async def __call__(self, scope: Scope, receive: Receive, send: Send) -> None:
|
||||
if scope["type"] != "http" or "/metrics" not in scope.get("path", ""):
|
||||
await self.app(scope, receive, send)
|
||||
return
|
||||
|
||||
if litellm.require_auth_for_metrics_endpoint is True:
|
||||
request = Request(scope, receive)
|
||||
api_key = request.headers.get("Authorization") or ""
|
||||
try:
|
||||
await user_api_key_auth(request=request, api_key=api_key)
|
||||
except Exception as e:
|
||||
# send 401 directly via ASGI protocol
|
||||
...
|
||||
return
|
||||
|
||||
await self.app(scope, receive, send)
|
||||
```
|
||||
|
||||
For the 99.9% of requests that aren't hitting `/metrics`, the middleware is now one dict lookup, one string check, and one function call. No objects allocated, no tasks spawned.
|
||||
|
||||
It's important to evaluate if the tools you're using are the right fit for the job as your software grows and handles more responsiblity. We're now putting in a static analysis check to prevent this from happening again with any newly introduced middlewares. If we find the use case is necessary then that's okay and we'll reevalute but for everything LiteLLM needs to do at the moment it's not.
|
||||
|
||||
This middleware change was one part of a broader optimization effort on the LiteLLM proxy. Across all optimizations combined, we've measured about a **30% reduction in proxy overhead** over the past two weeks.
|
||||
|
||||
---
|
||||
|
||||
<a id="footnote-1"></a>
|
||||
<sup>1</sup> [Starlette Middleware — BaseHTTPMiddleware](https://starlette.dev/middleware/#basehttpmiddleware)
|
||||
|
||||
<a id="footnote-2"></a>
|
||||
<sup>2</sup> [Apache HTTP server benchmarking tool (`ab`)](https://httpd.apache.org/docs/2.4/programs/ab.html)
|
||||
|
|
@ -1,142 +0,0 @@
|
|||
---
|
||||
slug: gemini_3_1_pro
|
||||
title: "DAY 0 Support: Gemini 3.1 Pro on LiteLLM"
|
||||
date: 2026-02-19T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
- krrish
|
||||
- ishaan-alt
|
||||
description: "Guide to using Gemini 3.1 Pro on LiteLLM Proxy and SDK with day 0 support."
|
||||
tags: [gemini, day 0 support, llms]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Gemini 3.1 Pro Day 0 Support
|
||||
|
||||
LiteLLM now supports `gemini-3.1-pro-preview` and all the new API changes along with it.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
## Deploy this version
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="docker" label="Docker">
|
||||
|
||||
``` showLineNumbers title="docker run litellm"
|
||||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
ghcr.io/berriai/litellm:main-v1.81.9-stable.gemini.3.1-pro
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="pip" label="Pip">
|
||||
|
||||
``` showLineNumbers title="pip install litellm"
|
||||
pip install litellm==v1.81.9-stable.gemini.3.1-pro
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## What's New
|
||||
|
||||
### 1. New Thinking Levels: `thinkingLevel` with MINIMAL & MEDIUM
|
||||
|
||||
Gemini 3.1 Pro introduces support for **medium** thinking level
|
||||
|
||||
LiteLLM automatically maps the OpenAI `reasoning_effort` parameter to Gemini's `thinkingLevel`, so you can use familiar `reasoning_effort` values (`minimal`, `low`, `medium`, `high`) without changing your code!
|
||||
|
||||
---
|
||||
## Supported Endpoints
|
||||
|
||||
LiteLLM provides **full end-to-end support** for Gemini 3.1 Pro on:
|
||||
|
||||
- ✅ `/v1/chat/completions` - OpenAI-compatible chat completions endpoint
|
||||
- ✅ `/v1/responses` - OpenAI Responses API endpoint (streaming and non-streaming)
|
||||
- ✅ [`/v1/messages`](../../docs/anthropic_unified) - Anthropic-compatible messages endpoint
|
||||
- ✅ `/v1/generateContent` – [Google Gemini API](../../docs/generateContent) compatible endpoint
|
||||
|
||||
All endpoints support:
|
||||
- Streaming and non-streaming responses
|
||||
- Function calling with thought signatures
|
||||
- Multi-turn conversations
|
||||
- All Gemini 3-specific features
|
||||
- Conversion of provider specific thinking related param to thinkingLevel
|
||||
|
||||
## Quick Start
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
**Basic Usage with MEDIUM thinking (NEW)**
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
# No need to make any changes to your code as we map openai reasoning param to thinkingLevel
|
||||
response = completion(
|
||||
model="gemini/gemini-3.1-pro-preview",
|
||||
messages=[{"role": "user", "content": "Solve this complex math problem: 25 * 4 + 10"}],
|
||||
reasoning_effort="medium", # NEW: MEDIUM thinking level
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gemini-3.1-pro-preview
|
||||
litellm_params:
|
||||
model: gemini/gemini-3.1-pro-preview
|
||||
api_key: os.environ/GEMINI_API_KEY
|
||||
- model_name: vertex-gemini-3.1-pro-preview
|
||||
litellm_params:
|
||||
model: vertex_ai/gemini-3.1-pro-preview
|
||||
```
|
||||
|
||||
**2. Start proxy**
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
**3. Call with MEDIUM thinking**
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer <YOUR-LITELLM-KEY>" \
|
||||
-d '{
|
||||
"model": "gemini-3.1-pro-preview",
|
||||
"messages": [{"role": "user", "content": "Complex reasoning task"}],
|
||||
"reasoning_effort": "medium"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
---
|
||||
|
||||
## `reasoning_effort` Mapping for Gemini 3+
|
||||
|
||||
| reasoning_effort | thinking_level |
|
||||
|------------------|----------------|
|
||||
| `minimal` | `minimal` |
|
||||
| `low` | `low` |
|
||||
| `medium` | `medium` |
|
||||
| `high` | `high` |
|
||||
| `disable` | `minimal` |
|
||||
| `none` | `minimal` |
|
||||
|
|
@ -1,975 +0,0 @@
|
|||
---
|
||||
slug: gemini_3
|
||||
title: "DAY 0 Support: Gemini 3 on LiteLLM"
|
||||
date: 2025-11-19T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
- krrish
|
||||
- ishaan-alt
|
||||
description: "Common questions and best practices for using gemini-3-pro-preview with LiteLLM Proxy and SDK."
|
||||
tags: [gemini, day 0 support, llms]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
:::info
|
||||
|
||||
This guide covers common questions and best practices for using `gemini-3-pro-preview` with LiteLLM Proxy and SDK.
|
||||
|
||||
:::
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
## Quick Start
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="Python SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
import os
|
||||
|
||||
os.environ["GEMINI_API_KEY"] = "your-api-key"
|
||||
|
||||
response = completion(
|
||||
model="gemini/gemini-3-pro-preview",
|
||||
messages=[{"role": "user", "content": "Hello!"}],
|
||||
reasoning_effort="low"
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Add to config.yaml:**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gemini-3-pro-preview
|
||||
litellm_params:
|
||||
model: gemini/gemini-3-pro-preview
|
||||
api_key: os.environ/GEMINI_API_KEY
|
||||
```
|
||||
|
||||
**2. Start proxy:**
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
**3. Make request:**
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gemini-3-pro-preview",
|
||||
"messages": [{"role": "user", "content": "Hello!"}],
|
||||
"reasoning_effort": "low"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Supported Endpoints
|
||||
|
||||
LiteLLM provides **full end-to-end support** for Gemini 3 Pro Preview on:
|
||||
|
||||
- ✅ `/v1/chat/completions` - OpenAI-compatible chat completions endpoint
|
||||
- ✅ `/v1/responses` - OpenAI Responses API endpoint (streaming and non-streaming)
|
||||
- ✅ [`/v1/messages`](../../docs/anthropic_unified) - Anthropic-compatible messages endpoint
|
||||
- ✅ `/v1/generateContent` – [Google Gemini API](https://cloud.google.com/vertex-ai/docs/generative-ai/model-reference/gemini#rest) compatible endpoint (for code, see: `client.models.generate_content(...)`)
|
||||
|
||||
All endpoints support:
|
||||
- Streaming and non-streaming responses
|
||||
- Function calling with thought signatures
|
||||
- Multi-turn conversations
|
||||
- All Gemini 3-specific features
|
||||
|
||||
## Thought Signatures
|
||||
|
||||
#### What are Thought Signatures?
|
||||
|
||||
Thought signatures are encrypted representations of the model's internal reasoning process. They're essential for maintaining context across multi-turn conversations, especially with function calling.
|
||||
|
||||
#### How Thought Signatures Work
|
||||
|
||||
1. **Automatic Extraction**: When Gemini 3 returns a function call, LiteLLM automatically extracts the `thought_signature` from the response
|
||||
2. **Storage**: Thought signatures are stored in `provider_specific_fields.thought_signature` of tool calls
|
||||
3. **Automatic Preservation**: When you include the assistant's message in conversation history, LiteLLM automatically preserves and returns thought signatures to Gemini
|
||||
|
||||
## Example: Multi-Turn Function Calling
|
||||
|
||||
#### Streaming with Thought Signatures
|
||||
|
||||
When using streaming mode with `stream_chunk_builder()`, thought signatures are now automatically preserved:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="streaming" label="Streaming SDK">
|
||||
|
||||
```python
|
||||
import os
|
||||
import litellm
|
||||
from litellm import completion
|
||||
|
||||
os.environ["GEMINI_API_KEY"] = "your-api-key"
|
||||
|
||||
MODEL = "gemini/gemini-3-pro-preview"
|
||||
|
||||
messages = [
|
||||
{"role": "system", "content": "You are a helpful assistant. Use the calculate tool."},
|
||||
{"role": "user", "content": "What is 2+2?"},
|
||||
]
|
||||
|
||||
tools = [{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "calculate",
|
||||
"description": "Calculate a mathematical expression",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {"expression": {"type": "string"}},
|
||||
"required": ["expression"],
|
||||
},
|
||||
},
|
||||
}]
|
||||
|
||||
print("Step 1: Sending request with stream=True...")
|
||||
response = completion(
|
||||
model=MODEL,
|
||||
messages=messages,
|
||||
stream=True,
|
||||
tools=tools,
|
||||
reasoning_effort="low"
|
||||
)
|
||||
|
||||
# Collect all chunks
|
||||
chunks = []
|
||||
for part in response:
|
||||
chunks.append(part)
|
||||
|
||||
# Reconstruct message using stream_chunk_builder
|
||||
# Thought signatures are now preserved automatically!
|
||||
full_response = litellm.stream_chunk_builder(chunks, messages=messages)
|
||||
print(f"Full response: {full_response}")
|
||||
|
||||
assistant_msg = full_response.choices[0].message
|
||||
|
||||
# ✅ Thought signature is now preserved in provider_specific_fields
|
||||
if assistant_msg.tool_calls and assistant_msg.tool_calls[0].provider_specific_fields:
|
||||
thought_sig = assistant_msg.tool_calls[0].provider_specific_fields.get("thought_signature")
|
||||
print(f"Thought signature preserved: {thought_sig is not None}")
|
||||
|
||||
# Append assistant message (includes thought signatures automatically)
|
||||
messages.append(assistant_msg)
|
||||
|
||||
# Mock tool execution
|
||||
messages.append({
|
||||
"role": "tool",
|
||||
"content": "4",
|
||||
"tool_call_id": assistant_msg.tool_calls[0].id
|
||||
})
|
||||
|
||||
print("\nStep 2: Sending tool result back to model...")
|
||||
response_2 = completion(
|
||||
model=MODEL,
|
||||
messages=messages,
|
||||
stream=True,
|
||||
tools=tools,
|
||||
reasoning_effort="low"
|
||||
)
|
||||
|
||||
for part in response_2:
|
||||
if part.choices[0].delta.content:
|
||||
print(part.choices[0].delta.content, end="")
|
||||
print() # New line
|
||||
```
|
||||
|
||||
**Key Points:**
|
||||
- ✅ `stream_chunk_builder()` now preserves `provider_specific_fields` including thought signatures
|
||||
- ✅ Thought signatures are automatically included when appending `assistant_msg` to conversation history
|
||||
- ✅ Multi-turn conversations work seamlessly with streaming
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sdk" label="Non-Streaming SDK">
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
import json
|
||||
|
||||
client = OpenAI(api_key="sk-1234", base_url="http://localhost:4000")
|
||||
|
||||
# Define tools
|
||||
tools = [
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get the current weather",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {"type": "string"}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
|
||||
# Step 1: Initial request
|
||||
messages = [{"role": "user", "content": "What's the weather in Tokyo?"}]
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="gemini-3-pro-preview",
|
||||
messages=messages,
|
||||
tools=tools,
|
||||
reasoning_effort="low"
|
||||
)
|
||||
|
||||
# Step 2: Append assistant message (thought signatures automatically preserved)
|
||||
messages.append(response.choices[0].message)
|
||||
|
||||
# Step 3: Execute tool and append result
|
||||
for tool_call in response.choices[0].message.tool_calls:
|
||||
if tool_call.function.name == "get_weather":
|
||||
result = {"temperature": 30, "unit": "celsius"}
|
||||
messages.append({
|
||||
"role": "tool",
|
||||
"content": json.dumps(result),
|
||||
"tool_call_id": tool_call.id
|
||||
})
|
||||
|
||||
# Step 4: Follow-up request (thought signatures automatically included)
|
||||
response2 = client.chat.completions.create(
|
||||
model="gemini-3-pro-preview",
|
||||
messages=messages,
|
||||
tools=tools,
|
||||
reasoning_effort="low"
|
||||
)
|
||||
|
||||
print(response2.choices[0].message.content)
|
||||
```
|
||||
|
||||
**Key Points:**
|
||||
- ✅ Thought signatures are automatically extracted from `response.choices[0].message.tool_calls[].provider_specific_fields.thought_signature`
|
||||
- ✅ When you append `response.choices[0].message` to your conversation history, thought signatures are automatically preserved
|
||||
- ✅ You don't need to manually extract or manage thought signatures
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="cURL">
|
||||
|
||||
```bash
|
||||
# Step 1: Initial request
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gemini-3-pro-preview",
|
||||
"messages": [
|
||||
{"role": "user", "content": "What'\''s the weather in Tokyo?"}
|
||||
],
|
||||
"tools": [
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get the current weather",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {"type": "string"}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
}
|
||||
}
|
||||
],
|
||||
"reasoning_effort": "low"
|
||||
}'
|
||||
```
|
||||
|
||||
**Response includes thought signature:**
|
||||
|
||||
```json
|
||||
{
|
||||
"choices": [{
|
||||
"message": {
|
||||
"role": "assistant",
|
||||
"tool_calls": [{
|
||||
"id": "call_abc123",
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"arguments": "{\"location\": \"Tokyo\"}"
|
||||
},
|
||||
"provider_specific_fields": {
|
||||
"thought_signature": "CpcHAdHtim9+q4rstcbvQC0ic4x1/vqQlCJWgE+UZ6dTLYGHMMBkF/AxqL5UmP6SY46uYC8t4BTFiXG5zkw6EMJ..."
|
||||
}
|
||||
}]
|
||||
}
|
||||
}]
|
||||
}
|
||||
```
|
||||
|
||||
```bash
|
||||
# Step 2: Follow-up request (include assistant message with thought signature)
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gemini-3-pro-preview",
|
||||
"messages": [
|
||||
{"role": "user", "content": "What'\''s the weather in Tokyo?"},
|
||||
{
|
||||
"role": "assistant",
|
||||
"content": null,
|
||||
"tool_calls": [{
|
||||
"id": "call_abc123",
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"arguments": "{\"location\": \"Tokyo\"}"
|
||||
},
|
||||
"provider_specific_fields": {
|
||||
"thought_signature": "CpcHAdHtim9+q4rstcbvQC0ic4x1/vqQlCJWgE+UZ6dTLYGHMMBkF/AxqL5UmP6SY46uYC8t4BTFiXG5zkw6EMJ..."
|
||||
}
|
||||
}]
|
||||
},
|
||||
{
|
||||
"role": "tool",
|
||||
"content": "{\"temperature\": 30, \"unit\": \"celsius\"}",
|
||||
"tool_call_id": "call_abc123"
|
||||
}
|
||||
],
|
||||
"tools": [...],
|
||||
"reasoning_effort": "low"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
#### Important Notes on Thought Signatures
|
||||
|
||||
1. **Automatic Handling**: LiteLLM automatically extracts and preserves thought signatures. You don't need to manually manage them.
|
||||
|
||||
2. **Parallel Function Calls**: When the model makes parallel function calls, only the **first function call** has a thought signature.
|
||||
|
||||
3. **Sequential Function Calls**: In multi-step function calling, each step's first function call has its own thought signature that must be preserved.
|
||||
|
||||
4. **Required for Context**: Thought signatures are essential for maintaining reasoning context. Without them, the model may lose context of its previous reasoning.
|
||||
|
||||
## Conversation History: Switching from Non-Gemini-3 Models
|
||||
|
||||
#### Common Question: Will switching from a non-Gemini-3 model to Gemini-3 break conversation history?
|
||||
|
||||
**Answer: No!** LiteLLM automatically handles this by adding dummy thought signatures when needed.
|
||||
|
||||
#### How It Works
|
||||
|
||||
When you switch from a model that doesn't use thought signatures (e.g., `gemini-2.5-flash`) to Gemini 3, LiteLLM:
|
||||
|
||||
1. **Detects missing signatures**: Identifies assistant messages with tool calls that lack thought signatures
|
||||
2. **Adds dummy signature**: Automatically injects a dummy thought signature (`skip_thought_signature_validator`) for compatibility
|
||||
3. **Maintains conversation flow**: Your conversation history continues to work seamlessly
|
||||
|
||||
#### Example: Switching Models Mid-Conversation
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="Python SDK">
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(api_key="sk-1234", base_url="http://localhost:4000")
|
||||
|
||||
# Step 1: Start with gemini-2.5-flash (no thought signatures)
|
||||
messages = [{"role": "user", "content": "What's the weather?"}]
|
||||
|
||||
response1 = client.chat.completions.create(
|
||||
model="gemini-2.5-flash",
|
||||
messages=messages,
|
||||
tools=[...],
|
||||
reasoning_effort="low"
|
||||
)
|
||||
|
||||
# Append assistant message (no tool call thought signature from gemini-2.5-flash)
|
||||
messages.append(response1.choices[0].message)
|
||||
|
||||
# Step 2: Switch to gemini-3-pro-preview
|
||||
# LiteLLM automatically adds dummy thought signature to the previous assistant message
|
||||
response2 = client.chat.completions.create(
|
||||
model="gemini-3-pro-preview", # 👈 Switched model
|
||||
messages=messages, # 👈 Same conversation history
|
||||
tools=[...],
|
||||
reasoning_effort="low"
|
||||
)
|
||||
|
||||
# ✅ Works seamlessly! No errors, no breaking changes
|
||||
print(response2.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="cURL">
|
||||
|
||||
```bash
|
||||
# Step 1: Start with gemini-2.5-flash
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gemini-2.5-flash",
|
||||
"messages": [{"role": "user", "content": "What'\''s the weather?"}],
|
||||
"tools": [...],
|
||||
"reasoning_effort": "low"
|
||||
}'
|
||||
|
||||
# Step 2: Switch to gemini-3-pro-preview with same conversation history
|
||||
# LiteLLM automatically handles the missing thought signature
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gemini-3-pro-preview", # 👈 Switched model
|
||||
"messages": [
|
||||
{"role": "user", "content": "What'\''s the weather?"},
|
||||
{
|
||||
"role": "assistant",
|
||||
"tool_calls": [...] # 👈 No thought_signature from gemini-2.5-flash
|
||||
}
|
||||
],
|
||||
"tools": [...],
|
||||
"reasoning_effort": "low"
|
||||
}'
|
||||
# ✅ Works! LiteLLM adds dummy signature automatically
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
#### Dummy Signature Details
|
||||
|
||||
The dummy signature used is: `base64("skip_thought_signature_validator")`
|
||||
|
||||
This is the recommended approach by Google for handling conversation history from models that don't support thought signatures. It allows Gemini 3 to:
|
||||
- Accept the conversation history without validation errors
|
||||
- Continue the conversation seamlessly
|
||||
- Maintain context across model switches
|
||||
|
||||
## Thinking Level Parameter
|
||||
|
||||
#### How `reasoning_effort` Maps to `thinking_level`
|
||||
|
||||
For Gemini 3 Pro Preview, LiteLLM automatically maps `reasoning_effort` to the new `thinking_level` parameter:
|
||||
|
||||
| `reasoning_effort` | `thinking_level` | Notes |
|
||||
|-------------------|------------------|-------|
|
||||
| `"minimal"` | `"low"` | Maps to low thinking level |
|
||||
| `"low"` | `"low"` | Default for most use cases |
|
||||
| `"medium"` | `"high"` | Medium not available yet, maps to high |
|
||||
| `"high"` | `"high"` | Maximum reasoning depth |
|
||||
| `"disable"` | `"low"` | Gemini 3 cannot fully disable thinking |
|
||||
| `"none"` | `"low"` | Gemini 3 cannot fully disable thinking |
|
||||
|
||||
#### Default Behavior
|
||||
|
||||
If you don't specify `reasoning_effort`, LiteLLM automatically sets `thinking_level="low"` for Gemini 3 models, to avoid high costs.
|
||||
|
||||
### Example Usage
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="Python SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
# Low thinking level (faster, lower cost)
|
||||
response = completion(
|
||||
model="gemini/gemini-3-pro-preview",
|
||||
messages=[{"role": "user", "content": "What's the weather?"}],
|
||||
reasoning_effort="low" # Maps to thinking_level="low"
|
||||
)
|
||||
|
||||
# High thinking level (deeper reasoning, higher cost)
|
||||
response = completion(
|
||||
model="gemini/gemini-3-pro-preview",
|
||||
messages=[{"role": "user", "content": "Solve this complex math problem step by step."}],
|
||||
reasoning_effort="high" # Maps to thinking_level="high"
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
```bash
|
||||
# Low thinking level
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gemini-3-pro-preview",
|
||||
"messages": [{"role": "user", "content": "What'\''s the weather?"}],
|
||||
"reasoning_effort": "low"
|
||||
}'
|
||||
|
||||
# High thinking level
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gemini-3-pro-preview",
|
||||
"messages": [{"role": "user", "content": "Solve this complex problem."}],
|
||||
"reasoning_effort": "high"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Important Notes
|
||||
|
||||
1. **Gemini 3 Cannot Disable Thinking**: Unlike Gemini 2.5 models, Gemini 3 cannot fully disable thinking. Even when you set `reasoning_effort="none"` or `"disable"`, it maps to `thinking_level="low"`.
|
||||
|
||||
2. **Temperature Recommendation**: For Gemini 3 models, LiteLLM defaults `temperature` to `1.0` and strongly recommends keeping it at this default. Setting `temperature < 1.0` can cause:
|
||||
- Infinite loops
|
||||
- Degraded reasoning performance
|
||||
- Failure on complex tasks
|
||||
|
||||
3. **Automatic Defaults**: If you don't specify `reasoning_effort`, LiteLLM automatically sets `thinking_level="low"` for optimal performance.
|
||||
|
||||
## Cost Tracking: Prompt Caching & Context Window
|
||||
|
||||
LiteLLM provides comprehensive cost tracking for Gemini 3 Pro Preview, including support for prompt caching and tiered pricing based on context window size.
|
||||
|
||||
### Prompt Caching Cost Tracking
|
||||
|
||||
Gemini 3 supports prompt caching, which allows you to cache frequently used prompt prefixes to reduce costs. LiteLLM automatically tracks and calculates costs for:
|
||||
|
||||
- **Cache Hit Tokens**: Tokens that are read from cache (charged at a lower rate)
|
||||
- **Cache Creation Tokens**: Tokens that are written to cache (one-time cost)
|
||||
- **Text Tokens**: Regular prompt tokens that are processed normally
|
||||
|
||||
#### How It Works
|
||||
|
||||
LiteLLM extracts caching information from the `prompt_tokens_details` field in the usage object:
|
||||
|
||||
```python
|
||||
{
|
||||
"usage": {
|
||||
"prompt_tokens": 50000,
|
||||
"completion_tokens": 1000,
|
||||
"total_tokens": 51000,
|
||||
"prompt_tokens_details": {
|
||||
"cached_tokens": 30000, # Cache hit tokens
|
||||
"cache_creation_tokens": 5000, # Tokens written to cache
|
||||
"text_tokens": 15000 # Regular processed tokens
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Context Window Tiered Pricing
|
||||
|
||||
Gemini 3 Pro Preview supports up to 1M tokens of context, with tiered pricing that automatically applies when your prompt exceeds 200k tokens.
|
||||
|
||||
#### Automatic Tier Detection
|
||||
|
||||
LiteLLM automatically detects when your prompt exceeds the 200k token threshold and applies the appropriate tiered pricing:
|
||||
|
||||
```python
|
||||
from litellm import completion_cost
|
||||
|
||||
# Example: Small prompt (< 200k tokens)
|
||||
response_small = completion(
|
||||
model="gemini/gemini-3-pro-preview",
|
||||
messages=[{"role": "user", "content": "Hello!"}]
|
||||
)
|
||||
# Uses base pricing: $0.000002/input token, $0.000012/output token
|
||||
|
||||
# Example: Large prompt (> 200k tokens)
|
||||
response_large = completion(
|
||||
model="gemini/gemini-3-pro-preview",
|
||||
messages=[{"role": "user", "content": "..." * 250000}] # 250k tokens
|
||||
)
|
||||
# Automatically uses tiered pricing: $0.000004/input token, $0.000018/output token
|
||||
```
|
||||
|
||||
#### Cost Breakdown
|
||||
|
||||
The cost calculation includes:
|
||||
|
||||
1. **Text Processing Cost**: Regular tokens processed at base or tiered rate
|
||||
2. **Cache Read Cost**: Cached tokens read at discounted rate
|
||||
3. **Cache Creation Cost**: One-time cost for writing tokens to cache (applies tiered rate if above 200k)
|
||||
4. **Output Cost**: Generated tokens at base or tiered rate
|
||||
|
||||
### Example: Viewing Cost Breakdown
|
||||
|
||||
You can view the detailed cost breakdown using LiteLLM's cost tracking:
|
||||
|
||||
```python
|
||||
from litellm import completion, completion_cost
|
||||
|
||||
response = completion(
|
||||
model="gemini/gemini-3-pro-preview",
|
||||
messages=[{"role": "user", "content": "Explain prompt caching"}],
|
||||
caching=True # Enable prompt caching
|
||||
)
|
||||
|
||||
# Get total cost
|
||||
total_cost = completion_cost(completion_response=response)
|
||||
print(f"Total cost: ${total_cost:.6f}")
|
||||
|
||||
# Access usage details
|
||||
usage = response.usage
|
||||
print(f"Prompt tokens: {usage.prompt_tokens}")
|
||||
print(f"Completion tokens: {usage.completion_tokens}")
|
||||
|
||||
# Access caching details
|
||||
if usage.prompt_tokens_details:
|
||||
print(f"Cache hit tokens: {usage.prompt_tokens_details.cached_tokens}")
|
||||
print(f"Cache creation tokens: {usage.prompt_tokens_details.cache_creation_tokens}")
|
||||
print(f"Text tokens: {usage.prompt_tokens_details.text_tokens}")
|
||||
```
|
||||
|
||||
### Cost Optimization Tips
|
||||
|
||||
1. **Use Prompt Caching**: For repeated prompt prefixes, enable caching to reduce costs by up to 90% for cached portions
|
||||
2. **Monitor Context Size**: Be aware that prompts above 200k tokens use tiered pricing (2x for input, 1.5x for output)
|
||||
3. **Cache Management**: Cache creation tokens are charged once when writing to cache, then subsequent reads are much cheaper
|
||||
4. **Track Usage**: Use LiteLLM's built-in cost tracking to monitor spending across different token types
|
||||
|
||||
### Integration with LiteLLM Proxy
|
||||
|
||||
When using LiteLLM Proxy, all cost tracking is automatically logged and available through:
|
||||
|
||||
- **Usage Logs**: Detailed token and cost breakdowns in proxy logs
|
||||
- **Budget Management**: Set budgets and alerts based on actual usage
|
||||
- **Analytics Dashboard**: View cost trends and breakdowns by token type
|
||||
|
||||
```yaml
|
||||
# config.yaml
|
||||
model_list:
|
||||
- model_name: gemini-3-pro-preview
|
||||
litellm_params:
|
||||
model: gemini/gemini-3-pro-preview
|
||||
api_key: os.environ/GEMINI_API_KEY
|
||||
|
||||
litellm_settings:
|
||||
# Enable detailed cost tracking
|
||||
success_callback: ["langfuse"] # or your preferred logging service
|
||||
```
|
||||
|
||||
## Using with Claude Code CLI
|
||||
|
||||
You can use `gemini-3-pro-preview` with **Claude Code CLI** - Anthropic's command-line interface. This allows you to use Gemini 3 Pro Preview with Claude Code's native syntax and workflows.
|
||||
|
||||
### Setup
|
||||
|
||||
**1. Add Gemini 3 Pro Preview to your `config.yaml`:**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gemini-3-pro-preview
|
||||
litellm_params:
|
||||
model: gemini/gemini-3-pro-preview
|
||||
api_key: os.environ/GEMINI_API_KEY
|
||||
|
||||
litellm_settings:
|
||||
master_key: os.environ/LITELLM_MASTER_KEY
|
||||
```
|
||||
|
||||
**2. Set environment variables:**
|
||||
|
||||
```bash
|
||||
export GEMINI_API_KEY="your-gemini-api-key"
|
||||
export LITELLM_MASTER_KEY="sk-1234567890" # Generate a secure key
|
||||
```
|
||||
|
||||
**3. Start LiteLLM Proxy:**
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
**4. Configure Claude Code to use LiteLLM Proxy:**
|
||||
|
||||
```bash
|
||||
export ANTHROPIC_BASE_URL="http://0.0.0.0:4000"
|
||||
export ANTHROPIC_AUTH_TOKEN="$LITELLM_MASTER_KEY"
|
||||
```
|
||||
|
||||
**5. Use Gemini 3 Pro Preview with Claude Code:**
|
||||
|
||||
```bash
|
||||
# Claude Code will use gemini-3-pro-preview from your LiteLLM proxy
|
||||
claude --model gemini-3-pro-preview
|
||||
|
||||
```
|
||||
|
||||
### Example Usage
|
||||
|
||||
Once configured, you can interact with Gemini 3 Pro Preview using Claude Code's native interface:
|
||||
|
||||
```bash
|
||||
$ claude --model gemini-3-pro-preview
|
||||
> Explain how thought signatures work in multi-turn conversations.
|
||||
|
||||
# Gemini 3 Pro Preview responds through Claude Code interface
|
||||
```
|
||||
|
||||
### Benefits
|
||||
|
||||
- ✅ **Native Claude Code Experience**: Use Gemini 3 Pro Preview with Claude Code's familiar CLI interface
|
||||
- ✅ **Unified Authentication**: Single API key for all models through LiteLLM proxy
|
||||
- ✅ **Cost Tracking**: All usage tracked through LiteLLM's centralized logging
|
||||
- ✅ **Seamless Model Switching**: Easily switch between Claude and Gemini models
|
||||
- ✅ **Full Feature Support**: All Gemini 3 features (thought signatures, function calling, etc.) work through Claude Code
|
||||
|
||||
### Troubleshooting
|
||||
|
||||
**Claude Code not finding the model:**
|
||||
- Ensure the model name in Claude Code matches exactly: `gemini-3-pro-preview`
|
||||
- Verify your proxy is running: `curl http://0.0.0.0:4000/health`
|
||||
- Check that `ANTHROPIC_BASE_URL` points to your LiteLLM proxy
|
||||
|
||||
**Authentication errors:**
|
||||
- Verify `ANTHROPIC_AUTH_TOKEN` matches your LiteLLM master key
|
||||
- Ensure `GEMINI_API_KEY` is set correctly
|
||||
- Check LiteLLM proxy logs for detailed error messages
|
||||
|
||||
## Responses API Support
|
||||
|
||||
LiteLLM fully supports the OpenAI Responses API for Gemini 3 Pro Preview, including both streaming and non-streaming modes. The Responses API provides a structured way to handle multi-turn conversations with function calling, and LiteLLM automatically preserves thought signatures throughout the conversation.
|
||||
|
||||
### Example: Using Responses API with Gemini 3
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="Non-Streaming">
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
import json
|
||||
|
||||
client = OpenAI()
|
||||
|
||||
# 1. Define a list of callable tools for the model
|
||||
tools = [
|
||||
{
|
||||
"type": "function",
|
||||
"name": "get_horoscope",
|
||||
"description": "Get today's horoscope for an astrological sign.",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"sign": {
|
||||
"type": "string",
|
||||
"description": "An astrological sign like Taurus or Aquarius",
|
||||
},
|
||||
},
|
||||
"required": ["sign"],
|
||||
},
|
||||
},
|
||||
]
|
||||
|
||||
def get_horoscope(sign):
|
||||
return f"{sign}: Next Tuesday you will befriend a baby otter."
|
||||
|
||||
# Create a running input list we will add to over time
|
||||
input_list = [
|
||||
{"role": "user", "content": "What is my horoscope? I am an Aquarius."}
|
||||
]
|
||||
|
||||
# 2. Prompt the model with tools defined
|
||||
response = client.responses.create(
|
||||
model="gemini-3-pro-preview",
|
||||
tools=tools,
|
||||
input=input_list,
|
||||
)
|
||||
|
||||
# Save function call outputs for subsequent requests
|
||||
input_list += response.output
|
||||
|
||||
for item in response.output:
|
||||
if item.type == "function_call":
|
||||
if item.name == "get_horoscope":
|
||||
# 3. Execute the function logic for get_horoscope
|
||||
horoscope = get_horoscope(json.loads(item.arguments))
|
||||
|
||||
# 4. Provide function call results to the model
|
||||
input_list.append({
|
||||
"type": "function_call_output",
|
||||
"call_id": item.call_id,
|
||||
"output": json.dumps({
|
||||
"horoscope": horoscope
|
||||
})
|
||||
})
|
||||
|
||||
print("Final input:")
|
||||
print(input_list)
|
||||
|
||||
response = client.responses.create(
|
||||
model="gemini-3-pro-preview",
|
||||
instructions="Respond only with a horoscope generated by a tool.",
|
||||
tools=tools,
|
||||
input=input_list,
|
||||
)
|
||||
|
||||
# 5. The model should be able to give a response!
|
||||
print("Final output:")
|
||||
print(response.model_dump_json(indent=2))
|
||||
print("\n" + response.output_text)
|
||||
```
|
||||
|
||||
**Key Points:**
|
||||
- ✅ Thought signatures are automatically preserved in function calls
|
||||
- ✅ Works seamlessly with multi-turn conversations
|
||||
- ✅ All Gemini 3-specific features are fully supported
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="streaming" label="Streaming">
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
import json
|
||||
|
||||
client = OpenAI()
|
||||
|
||||
tools = [
|
||||
{
|
||||
"type": "function",
|
||||
"name": "get_horoscope",
|
||||
"description": "Get today's horoscope for an astrological sign.",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"sign": {
|
||||
"type": "string",
|
||||
"description": "An astrological sign like Taurus or Aquarius",
|
||||
},
|
||||
},
|
||||
"required": ["sign"],
|
||||
},
|
||||
},
|
||||
]
|
||||
|
||||
def get_horoscope(sign):
|
||||
return f"{sign}: Next Tuesday you will befriend a baby otter."
|
||||
|
||||
input_list = [
|
||||
{"role": "user", "content": "What is my horoscope? I am an Aquarius."}
|
||||
]
|
||||
|
||||
# Streaming mode
|
||||
response = client.responses.create(
|
||||
model="gemini-3-pro-preview",
|
||||
tools=tools,
|
||||
input=input_list,
|
||||
stream=True,
|
||||
)
|
||||
|
||||
# Collect all chunks
|
||||
chunks = []
|
||||
for chunk in response:
|
||||
chunks.append(chunk)
|
||||
# Process streaming chunks as they arrive
|
||||
print(chunk)
|
||||
|
||||
# Thought signatures are automatically preserved in streaming mode
|
||||
```
|
||||
|
||||
**Key Points:**
|
||||
- ✅ Streaming mode fully supported
|
||||
- ✅ Thought signatures preserved across streaming chunks
|
||||
- ✅ Real-time processing of function calls and responses
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Responses API Benefits
|
||||
|
||||
- ✅ **Structured Output**: Responses API provides a clear structure for handling function calls and multi-turn conversations
|
||||
- ✅ **Thought Signature Preservation**: LiteLLM automatically preserves thought signatures in both streaming and non-streaming modes
|
||||
- ✅ **Seamless Integration**: Works with existing OpenAI SDK patterns
|
||||
- ✅ **Full Feature Support**: All Gemini 3 features (thought signatures, function calling, reasoning) are fully supported
|
||||
|
||||
|
||||
## Best Practices
|
||||
|
||||
#### 1. Always Include Thought Signatures in Conversation History
|
||||
|
||||
When building multi-turn conversations with function calling:
|
||||
|
||||
✅ **Do:**
|
||||
```python
|
||||
# Append the full assistant message (includes thought signatures)
|
||||
messages.append(response.choices[0].message)
|
||||
```
|
||||
|
||||
❌ **Don't:**
|
||||
```python
|
||||
# Don't manually construct assistant messages without thought signatures
|
||||
messages.append({
|
||||
"role": "assistant",
|
||||
"tool_calls": [...] # Missing thought signatures!
|
||||
})
|
||||
```
|
||||
|
||||
#### 2. Use Appropriate Thinking Levels
|
||||
|
||||
- **`reasoning_effort="low"`**: For simple queries, quick responses, cost optimization
|
||||
- **`reasoning_effort="high"`**: For complex problems requiring deep reasoning
|
||||
|
||||
#### 3. Keep Temperature at Default
|
||||
|
||||
For Gemini 3 models, always use `temperature=1.0` (default). Lower temperatures can cause issues.
|
||||
|
||||
#### 4. Handle Model Switches Gracefully
|
||||
|
||||
When switching from non-Gemini-3 to Gemini-3:
|
||||
- ✅ LiteLLM automatically handles missing thought signatures
|
||||
- ✅ No manual intervention needed
|
||||
- ✅ Conversation history continues seamlessly
|
||||
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
#### Issue: Missing Thought Signatures
|
||||
|
||||
**Symptom**: Error when including assistant messages in conversation history
|
||||
|
||||
**Solution**: Ensure you're appending the full assistant message from the response:
|
||||
```python
|
||||
messages.append(response.choices[0].message) # ✅ Includes thought signatures
|
||||
```
|
||||
|
||||
#### Issue: Conversation Breaks When Switching Models
|
||||
|
||||
**Symptom**: Errors when switching from gemini-2.5-flash to gemini-3-pro-preview
|
||||
|
||||
**Solution**: This should work automatically! LiteLLM adds dummy signatures. If you see errors, ensure you're using the latest LiteLLM version.
|
||||
|
||||
#### Issue: Infinite Loops or Poor Performance
|
||||
|
||||
**Symptom**: Model gets stuck or produces poor results
|
||||
|
||||
**Solution**:
|
||||
- Ensure `temperature=1.0` (default for Gemini 3)
|
||||
- Check that `reasoning_effort` is set appropriately
|
||||
- Verify you're using the correct model name: `gemini/gemini-3-pro-preview`
|
||||
|
||||
## Additional Resources
|
||||
|
||||
- [Gemini Provider Documentation](../../docs/providers/gemini)
|
||||
- [Thought Signatures Guide](../../docs/providers/gemini#thought-signatures)
|
||||
- [Reasoning Content Documentation](../../docs/reasoning_content)
|
||||
- [Function Calling Guide](../../docs/completion/function_call)
|
||||
|
|
@ -1,168 +0,0 @@
|
|||
---
|
||||
slug: gemini_3_1_flash_lite_preview
|
||||
title: "DAY 0 Support: Gemini 3.1 Flash Lite Preview on LiteLLM"
|
||||
date: 2026-03-03T08:00:00
|
||||
authors:
|
||||
- sameer
|
||||
- krrish
|
||||
- ishaan-alt
|
||||
description: "Guide to using Gemini 3.1 Flash Lite Preview on LiteLLM Proxy and SDK with day 0 support."
|
||||
tags: [gemini, day 0 support, llms, supernova]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Gemini 3.1 Flash Lite Preview Day 0 Support
|
||||
|
||||
LiteLLM now supports `gemini-3.1-flash-lite-preview` with full day 0 support!
|
||||
|
||||
:::note
|
||||
If you only want cost tracking, you need no change in your current Litellm version. But if you want the support for new features introduced along with it like thinking levels, you will need to use v1.80.8-stable.1 or above.
|
||||
:::
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
## Deploy this version
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="docker" label="Docker">
|
||||
|
||||
``` showLineNumbers title="docker run litellm"
|
||||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
ghcr.io/berriai/litellm:main-v1.80.8-stable.1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="pip" label="Pip">
|
||||
|
||||
``` showLineNumbers title="pip install litellm"
|
||||
pip install litellm==v1.80.8-stable.1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## What's New
|
||||
|
||||
Supports all four thinking levels:
|
||||
- **MINIMAL**: Ultra-fast responses with minimal reasoning
|
||||
- **LOW**: Simple instruction following
|
||||
- **MEDIUM**: Balanced reasoning for complex tasks
|
||||
- **HIGH**: Maximum reasoning depth (dynamic)
|
||||
|
||||
---
|
||||
|
||||
## Quick Start
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
**Basic Usage**
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="gemini/gemini-3.1-flash-lite-preview",
|
||||
messages=[{"role": "user", "content": "Extract key entities from this text: ..."}],
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
**With Thinking Levels**
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
# Use MEDIUM thinking for complex reasoning tasks
|
||||
response = completion(
|
||||
model="gemini/gemini-3.1-flash-lite-preview",
|
||||
messages=[{"role": "user", "content": "Analyze this dataset and identify patterns"}],
|
||||
reasoning_effort="medium", # low, medium , high
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gemini-3.1-flash-lite
|
||||
litellm_params:
|
||||
model: gemini/gemini-3.1-flash-lite-preview
|
||||
api_key: os.environ/GEMINI_API_KEY
|
||||
|
||||
# Or use Vertex AI
|
||||
- model_name: vertex-gemini-3.1-flash-lite
|
||||
litellm_params:
|
||||
model: vertex_ai/gemini-3.1-flash-lite-preview
|
||||
vertex_project: your-project-id
|
||||
vertex_location: us-central1
|
||||
```
|
||||
|
||||
**2. Start proxy**
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
**3. Make requests**
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer <YOUR-LITELLM-KEY>" \
|
||||
-d '{
|
||||
"model": "gemini-3.1-flash-lite",
|
||||
"messages": [{"role": "user", "content": "Extract structured data from this text"}],
|
||||
"reasoning_effort": "low"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
---
|
||||
|
||||
## Supported Endpoints
|
||||
|
||||
LiteLLM provides **full end-to-end support** for Gemini 3.1 Flash Lite Preview on:
|
||||
|
||||
- ✅ `/v1/chat/completions` - OpenAI-compatible chat completions endpoint
|
||||
- ✅ `/v1/responses` - OpenAI Responses API endpoint (streaming and non-streaming)
|
||||
- ✅ [`/v1/messages`](../../docs/anthropic_unified) - Anthropic-compatible messages endpoint
|
||||
- ✅ `/v1/generateContent` – [Google Gemini API](../../docs/generateContent) compatible endpoint
|
||||
|
||||
All endpoints support:
|
||||
- Streaming and non-streaming responses
|
||||
- Function calling with thought signatures
|
||||
- Multi-turn conversations
|
||||
- All Gemini 3-specific features (thinking levels, thought signatures)
|
||||
- Full multimodal support (text, image, audio, video)
|
||||
|
||||
---
|
||||
|
||||
## `reasoning_effort` Mapping for Gemini 3.1
|
||||
|
||||
LiteLLM automatically maps OpenAI's `reasoning_effort` parameter to Gemini's `thinkingLevel`:
|
||||
|
||||
| reasoning_effort | thinking_level | Use Case |
|
||||
|------------------|----------------|----------|
|
||||
| `minimal` | `minimal` | Ultra-fast responses, simple queries |
|
||||
| `low` | `low` | Basic instruction following |
|
||||
| `medium` | `medium` | Balanced reasoning for moderate complexity |
|
||||
| `high` | `high` | Maximum reasoning depth, complex problems |
|
||||
| `disable` | `minimal` | Disable extended reasoning |
|
||||
| `none` | `minimal` | No extended reasoning |
|
||||
|
|
@ -1,247 +0,0 @@
|
|||
---
|
||||
slug: gemini_3_flash
|
||||
title: "DAY 0 Support: Gemini 3 Flash on LiteLLM"
|
||||
date: 2025-12-17T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
- krrish
|
||||
- ishaan-alt
|
||||
description: "Guide to using Gemini 3 Flash on LiteLLM Proxy and SDK with day 0 support."
|
||||
tags: [gemini, day 0 support, llms]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Gemini 3 Flash Day 0 Support
|
||||
|
||||
LiteLLM now supports `gemini-3-flash-preview` and all the new API changes along with it.
|
||||
|
||||
:::note
|
||||
If you only want cost tracking, you need no change in your current Litellm version. But if you want the support for new features introduced along with it like thinking levels, you will need to use v1.80.8-stable.1 or above.
|
||||
:::
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
## Deploy this version
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="docker" label="Docker">
|
||||
|
||||
``` showLineNumbers title="docker run litellm"
|
||||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
ghcr.io/berriai/litellm:main-v1.80.8-stable.1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="pip" label="Pip">
|
||||
|
||||
``` showLineNumbers title="pip install litellm"
|
||||
pip install litellm==1.80.8.post1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## What's New
|
||||
|
||||
### 1. New Thinking Levels: `thinkingLevel` with MINIMAL & MEDIUM
|
||||
|
||||
Gemini 3 Flash introduces granular thinking control with `thinkingLevel` instead of `thinkingBudget`.
|
||||
- **MINIMAL**: Ultra-lightweight thinking for fast responses
|
||||
- **MEDIUM**: Balanced thinking for complex reasoning
|
||||
- **HIGH**: Maximum reasoning depth
|
||||
|
||||
LiteLLM automatically maps the OpenAI `reasoning_effort` parameter to Gemini's `thinkingLevel`, so you can use familiar `reasoning_effort` values (`minimal`, `low`, `medium`, `high`) without changing your code!
|
||||
|
||||
### 2. Thought Signatures
|
||||
|
||||
Like `gemini-3-pro`, this model also includes thought signatures for tool calls. LiteLLM handles signature extraction and embedding internally. [Learn more about thought signatures](../gemini_3/index.md#thought-signatures).
|
||||
|
||||
**Edge Case Handling**: If thought signatures are missing in the request, LiteLLM adds a dummy signature ensuring the API call doesn't break
|
||||
|
||||
---
|
||||
## Supported Endpoints
|
||||
|
||||
LiteLLM provides **full end-to-end support** for Gemini 3 Flash on:
|
||||
|
||||
- ✅ `/v1/chat/completions` - OpenAI-compatible chat completions endpoint
|
||||
- ✅ `/v1/responses` - OpenAI Responses API endpoint (streaming and non-streaming)
|
||||
- ✅ [`/v1/messages`](../../docs/anthropic_unified) - Anthropic-compatible messages endpoint
|
||||
- ✅ `/v1/generateContent` – [Google Gemini API](../../docs/generateContent) compatible endpoint
|
||||
All endpoints support:
|
||||
- Streaming and non-streaming responses
|
||||
- Function calling with thought signatures
|
||||
- Multi-turn conversations
|
||||
- All Gemini 3-specific features
|
||||
- Converstion of provider specific thinking related param to thinkingLevel
|
||||
|
||||
## Quick Start
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
**Basic Usage with MEDIUM thinking (NEW)**
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
# No need to make any changes to your code as we map openai reasoning param to thinkingLevel
|
||||
response = completion(
|
||||
model="gemini/gemini-3-flash-preview",
|
||||
messages=[{"role": "user", "content": "Solve this complex math problem: 25 * 4 + 10"}],
|
||||
reasoning_effort="medium", # NEW: MEDIUM thinking level
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gemini-3-flash
|
||||
litellm_params:
|
||||
model: gemini/gemini-3-flash-preview
|
||||
api_key: os.environ/GEMINI_API_KEY
|
||||
```
|
||||
|
||||
**2. Start proxy**
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
**3. Call with MEDIUM thinking**
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer <YOUR-LITELLM-KEY>" \
|
||||
-d '{
|
||||
"model": "gemini-3-flash",
|
||||
"messages": [{"role": "user", "content": "Complex reasoning task"}],
|
||||
"reasoning_effort": "medium"
|
||||
}'
|
||||
``'
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
---
|
||||
|
||||
## All `reasoning_effort` Levels
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="minimal" label="MINIMAL">
|
||||
|
||||
**Ultra-fast, minimal reasoning**
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="gemini/gemini-3-flash-preview",
|
||||
messages=[{"role": "user", "content": "What's 2+2?"}],
|
||||
reasoning_effort="minimal",
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="low" label="LOW">
|
||||
|
||||
**Simple instruction following**
|
||||
|
||||
```python
|
||||
response = completion(
|
||||
model="gemini/gemini-3-flash-preview",
|
||||
messages=[{"role": "user", "content": "Write a haiku about coding"}],
|
||||
reasoning_effort="low",
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="medium" label="MEDIUM (NEW)">
|
||||
|
||||
**Balanced reasoning for complex tasks** ✨
|
||||
|
||||
```python
|
||||
response = completion(
|
||||
model="gemini/gemini-3-flash-preview",
|
||||
messages=[{"role": "user", "content": "Analyze this dataset and find patterns"}],
|
||||
reasoning_effort="medium", # NEW!
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="high" label="HIGH">
|
||||
|
||||
**Maximum reasoning depth**
|
||||
|
||||
```python
|
||||
response = completion(
|
||||
model="gemini/gemini-3-flash-preview",
|
||||
messages=[{"role": "user", "content": "Prove this mathematical theorem"}],
|
||||
reasoning_effort="high",
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
---
|
||||
|
||||
## Key Features
|
||||
|
||||
✅ **Thinking Levels**: MINIMAL, LOW, MEDIUM, HIGH
|
||||
✅ **Thought Signatures**: Track reasoning with unique identifiers
|
||||
✅ **Seamless Integration**: Works with existing OpenAI-compatible client
|
||||
✅ **Backward Compatible**: Gemini 2.5 models continue using `thinkingBudget`
|
||||
|
||||
---
|
||||
|
||||
## Installation
|
||||
|
||||
```bash
|
||||
pip install litellm --upgrade
|
||||
```
|
||||
|
||||
```python
|
||||
import litellm
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="gemini/gemini-3-flash-preview",
|
||||
messages=[{"role": "user", "content": "Your question here"}],
|
||||
reasoning_effort="medium", # Use MEDIUM thinking
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
:::note
|
||||
If using this model via vertex_ai, keep the location as global as this is the only supported location as of now.
|
||||
:::
|
||||
|
||||
|
||||
## `reasoning_effort` Mapping for Gemini 3+
|
||||
|
||||
| reasoning_effort | thinking_level |
|
||||
|------------------|----------------|
|
||||
| `minimal` | `minimal` |
|
||||
| `low` | `low` |
|
||||
| `medium` | `medium` |
|
||||
| `high` | `high` |
|
||||
| `disable` | `minimal` |
|
||||
| `none` | `minimal` |
|
||||
|
|
@ -1,168 +0,0 @@
|
|||
---
|
||||
slug: gemini_embedding_2_multimodal
|
||||
title: "Gemini Embedding 2 Preview: Multimodal Embeddings on LiteLLM"
|
||||
date: 2025-03-11T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
description: "Generate embeddings from text, images, audio, video, and PDFs with gemini-embedding-2-preview on LiteLLM via Gemini API and Vertex AI."
|
||||
tags: [gemini, embeddings, multimodal, vertex ai]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Gemini Embedding 2 Preview: Multimodal Embeddings
|
||||
|
||||
LiteLLM now supports **multimodal embeddings** with `gemini-embedding-2-preview`—generating a single embedding from a mix of text, images, audio, video, and PDF content. Available via both the **Gemini API** (API key) and **Vertex AI** (GCP credentials).
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
## Supported Input Types
|
||||
|
||||
| Modality | Supported Formats |
|
||||
|----------|-------------------|
|
||||
| **Text** | Plain text |
|
||||
| **Image** | PNG, JPEG |
|
||||
| **Audio** | MP3, WAV |
|
||||
| **Video** | MP4, MOV |
|
||||
| **Documents** | PDF |
|
||||
|
||||
## Input Formats
|
||||
|
||||
LiteLLM accepts three input formats for multimodal content:
|
||||
|
||||
1. **Data URIs** – Base64-encoded inline: `data:image/png;base64,<encoded_data>`
|
||||
2. **GCS URLs** – Cloud Storage paths (Vertex AI): `gs://bucket/path/to/file.png`
|
||||
3. **Gemini File References** – Pre-uploaded files (Gemini API): `files/abc123`
|
||||
|
||||
## Quick Start
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="gemini" label="Gemini API">
|
||||
|
||||
```python
|
||||
from litellm import embedding
|
||||
import os
|
||||
|
||||
os.environ["GEMINI_API_KEY"] = "your-api-key"
|
||||
|
||||
# Text + Image (base64)
|
||||
response = embedding(
|
||||
model="gemini/gemini-embedding-2-preview",
|
||||
input=[
|
||||
"The food was delicious and the waiter...",
|
||||
"data:image/png;base64,iVBORw0KGgoAAAANSUhEUgAAAAgAAAAIAQMAAAD+wSzIAAAABlBMVEX///+/v7+jQ3Y5AAAADklEQVQI12P4AIX8EAgALgAD/aNpbtEAAAAASUVORK5CYII"
|
||||
],
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="vertex" label="Vertex AI">
|
||||
|
||||
```python
|
||||
import litellm
|
||||
from litellm import embedding
|
||||
|
||||
litellm.vertex_project = "your-project-id"
|
||||
litellm.vertex_location = "us-central1"
|
||||
|
||||
# Text + Image (GCS URL)
|
||||
response = embedding(
|
||||
model="vertex_ai/gemini-embedding-2-preview",
|
||||
input=[
|
||||
"Describe this image",
|
||||
"gs://my-bucket/images/photo.png"
|
||||
],
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Config (config.yaml)**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gemini-embedding-2-preview
|
||||
litellm_params:
|
||||
model: gemini/gemini-embedding-2-preview
|
||||
api_key: os.environ/GEMINI_API_KEY
|
||||
- model_name: vertex-gemini-embedding-2-preview
|
||||
litellm_params:
|
||||
model: vertex_ai/gemini-embedding-2-preview
|
||||
vertex_project: os.environ/VERTEXAI_PROJECT
|
||||
vertex_location: os.environ/VERTEXAI_LOCATION
|
||||
|
||||
general_settings:
|
||||
master_key: sk-1234
|
||||
```
|
||||
|
||||
**2. Start proxy**
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
**3. Call embeddings**
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/embeddings \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "gemini-embedding-2-preview",
|
||||
"input": [
|
||||
"The food was delicious and the waiter...",
|
||||
"data:image/png;base64,iVBORw0KGgoAAAANSUhEUgAAAAgAAAAIAQMAAAD+wSzIAAAABlBMVEX///+/v7+jQ3Y5AAAADklEQVQI12P4AIX8EAgALgAD/aNpbtEAAAAASUVORK5CYII"
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Input Format Examples
|
||||
|
||||
| Format | Example | Provider |
|
||||
|--------|---------|----------|
|
||||
| **Data URI** | `data:image/png;base64,...` | Gemini, Vertex AI |
|
||||
| **GCS URL** | `gs://bucket/path/image.png` | Vertex AI |
|
||||
| **File reference** | `files/abc123` | Gemini API only |
|
||||
|
||||
### Supported MIME Types for Data URIs
|
||||
|
||||
- **Images:** `image/png`, `image/jpeg`
|
||||
- **Audio:** `audio/mpeg`, `audio/wav`
|
||||
- **Video:** `video/mp4`, `video/quicktime`
|
||||
- **Documents:** `application/pdf`
|
||||
|
||||
### GCS URL MIME Inference
|
||||
|
||||
For Vertex AI, MIME types are inferred from file extensions:
|
||||
|
||||
- `.png` → `image/png`
|
||||
- `.jpg` / `.jpeg` → `image/jpeg`
|
||||
- `.mp3` → `audio/mpeg`
|
||||
- `.wav` → `audio/wav`
|
||||
- `.mp4` → `video/mp4`
|
||||
- `.mov` → `video/quicktime`
|
||||
- `.pdf` → `application/pdf`
|
||||
|
||||
## Optional Parameters
|
||||
|
||||
| Parameter | Description | Maps to |
|
||||
|-----------|-------------|---------|
|
||||
| `dimensions` | Output embedding size | `outputDimensionality` |
|
||||
|
||||
```python
|
||||
response = embedding(
|
||||
model="gemini/gemini-embedding-2-preview",
|
||||
input=["text to embed"],
|
||||
dimensions=768, # Optional: control output vector size
|
||||
)
|
||||
```
|
||||
|
|
@ -1,138 +0,0 @@
|
|||
---
|
||||
slug: gpt_5_3_codex
|
||||
title: "Day 0 Support: GPT-5.3-Codex"
|
||||
date: 2026-02-24T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
- krrish
|
||||
- ishaan-alt
|
||||
description: "Day 0 support for GPT-5.3-Codex on LiteLLM, including phase parameter handling for Responses API."
|
||||
tags: [openai, gpt-5.3-codex, codex, day 0 support]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
LiteLLM now supports GPT-5.3-Codex on Day 0, including support for the new assistant `phase` metadata on Responses API output items.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
## Why `phase` matters for GPT-5.3-Codex
|
||||
|
||||
`phase` appears on assistant output items and helps distinguish preamble/commentary turns from final closeout responses.
|
||||
|
||||
Reference: [Phase parameter docs](https://developers.openai.com/api/reference/overview)
|
||||
|
||||
Supported values:
|
||||
- `null`
|
||||
- `"commentary"`
|
||||
- `"final_answer"`
|
||||
|
||||
Important:
|
||||
- Persist assistant output items with `phase` exactly as returned.
|
||||
- Send those assistant items back on the next turn.
|
||||
- Do **not** add `phase` to user messages.
|
||||
|
||||
## Docker Image
|
||||
|
||||
```bash
|
||||
docker pull ghcr.io/berriai/litellm:v1.81.12-stable.gpt-5.3
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-5.3-codex
|
||||
litellm_params:
|
||||
model: openai/gpt-5.3-codex
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e ANTHROPIC_API_KEY=$OPENAI_API_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:v1.81.12-stable.gpt-5.3 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
|
||||
**3. Test it**
|
||||
|
||||
```bash
|
||||
curl -X POST "http://0.0.0.0:4000/v1/responses" \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer $LITELLM_KEY" \
|
||||
-d '{
|
||||
"model": "gpt-5.3-codex",
|
||||
"input": "Write a Python script that checks if a number is prime."
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Python Example: Persist `phase` with OpenAI Client + LiteLLM Base URL
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
base_url="http://0.0.0.0:4000/v1", # LiteLLM Proxy
|
||||
api_key="your-litellm-api-key",
|
||||
)
|
||||
|
||||
items = [] # Persist this per conversation/thread
|
||||
|
||||
|
||||
def _item_get(item, key, default=None):
|
||||
if isinstance(item, dict):
|
||||
return item.get(key, default)
|
||||
return getattr(item, key, default)
|
||||
|
||||
|
||||
def run_turn(user_text: str):
|
||||
global items
|
||||
|
||||
# User message: no phase field
|
||||
items.append(
|
||||
{
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{"type": "input_text", "text": user_text}],
|
||||
}
|
||||
)
|
||||
|
||||
resp = client.responses.create(
|
||||
model="gpt-5.3-codex",
|
||||
input=items,
|
||||
)
|
||||
|
||||
# Persist assistant output items verbatim, including phase
|
||||
for out_item in (resp.output or []):
|
||||
items.append(out_item)
|
||||
|
||||
# Optional: inspect latest phase for UI/telemetry routing
|
||||
latest_phase = None
|
||||
for out_item in reversed(resp.output or []):
|
||||
if _item_get(out_item, "type") == "output_item.done" and _item_get(out_item, "phase") is not None:
|
||||
latest_phase = _item_get(out_item, "phase")
|
||||
break
|
||||
|
||||
return resp, latest_phase
|
||||
```
|
||||
|
||||
## Notes
|
||||
|
||||
- Use `/v1/responses` for GPT Codex models.
|
||||
- Preserve full assistant output history for best multi-turn behavior.
|
||||
- If `phase` metadata is dropped during history reconstruction, output quality can degrade on long-running tasks.
|
||||
|
|
@ -1,90 +0,0 @@
|
|||
---
|
||||
slug: gpt_5_4
|
||||
title: "Day 0 Support: GPT-5.4"
|
||||
date: 2026-03-05T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
- krrish
|
||||
- ishaan-alt
|
||||
description: "GPT-5.4 model support in LiteLLM"
|
||||
tags: [openai, gpt-5.4, completion]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
LiteLLM now supports fully GPT-5.4!
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
## Docker Image
|
||||
|
||||
```bash
|
||||
docker pull ghcr.io/berriai/litellm:v1.81.14-stable.gpt-5.4_patch
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-5.4
|
||||
litellm_params:
|
||||
model: openai/gpt-5.4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e OPENAI_API_KEY=$OPENAI_API_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:v1.81.14-stable.gpt-5.4_patch \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it**
|
||||
|
||||
```bash
|
||||
curl -X POST "http://0.0.0.0:4000/chat/completions" \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer $LITELLM_KEY" \
|
||||
-d '{
|
||||
"model": "gpt-5.4",
|
||||
"messages": [
|
||||
{"role": "user", "content": "Write a Python function to check if a number is prime."}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sdk" label="LiteLLM SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="openai/gpt-5.4",
|
||||
messages=[
|
||||
{"role": "user", "content": "Write a Python function to check if a number is prime."}
|
||||
],
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Notes
|
||||
|
||||
- Restart your container to get the cost tracking for this model.
|
||||
- Use `/responses` for better model performance.
|
||||
- GPT-5.4 supports reasoning, function calling, vision, and tool-use — see the [OpenAI provider docs](../../docs/providers/openai) for advanced usage.
|
||||
|
|
@ -1,106 +0,0 @@
|
|||
---
|
||||
slug: gpt_5_4_mini_nano
|
||||
title: "Day 0 Support: GPT-5.4-mini and GPT-5.4-nano"
|
||||
date: 2026-03-17T10:00:00
|
||||
authors:
|
||||
- name: Sameer Kankute
|
||||
title: SWE @ LiteLLM (LLM Translation)
|
||||
url: https://www.linkedin.com/in/sameer-kankute/
|
||||
image_url: https://pbs.twimg.com/profile_images/2001352686994907136/ONgNuSk5_400x400.jpg
|
||||
- name: Krrish Dholakia
|
||||
title: "CEO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
description: "GPT-5.4-mini and GPT-5.4-nano model support in LiteLLM"
|
||||
tags: [openai, gpt-5.4-mini, gpt-5.4-nano, completion]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
LiteLLM now supports GPT-5.4-mini and GPT-5.4-nano — cost-effective models for simple completions and high-throughput workloads.
|
||||
|
||||
:::note
|
||||
If you're on **v1.82.3-stable** or above, you don't need any update to use these models.
|
||||
:::
|
||||
|
||||
## Usage
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-5.4-mini
|
||||
litellm_params:
|
||||
model: openai/gpt-5.4-mini
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
- model_name: gpt-5.4-nano
|
||||
litellm_params:
|
||||
model: openai/gpt-5.4-nano
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it**
|
||||
|
||||
```bash
|
||||
# GPT-5.4-mini
|
||||
curl -X POST "http://localhost:4000/v1/chat/completions" \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer $LITELLM_KEY" \
|
||||
-d '{
|
||||
"model": "gpt-5.4-mini",
|
||||
"messages": [{"role": "user", "content": "What is the capital of France?"}]
|
||||
}'
|
||||
|
||||
# GPT-5.4-nano
|
||||
curl -X POST "http://localhost:4000/v1/chat/completions" \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer $LITELLM_KEY" \
|
||||
-d '{
|
||||
"model": "gpt-5.4-nano",
|
||||
"messages": [{"role": "user", "content": "What is 2 + 2?"}]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sdk" label="LiteLLM SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
# GPT-5.4-mini
|
||||
response = completion(
|
||||
model="openai/gpt-5.4-mini",
|
||||
messages=[{"role": "user", "content": "What is the capital of France?"}],
|
||||
)
|
||||
print(response.choices[0].message.content)
|
||||
|
||||
# GPT-5.4-nano
|
||||
response = completion(
|
||||
model="openai/gpt-5.4-nano",
|
||||
messages=[{"role": "user", "content": "What is 2 + 2?"}],
|
||||
)
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Notes
|
||||
|
||||
- Both models support function calling, vision, and tool-use — see the [OpenAI provider docs](../../docs/providers/openai) for advanced usage.
|
||||
- GPT-5.4-nano is the most cost-effective option for simple tasks; GPT-5.4-mini offers a balance of speed and capability.
|
||||
|
|
@ -1,78 +0,0 @@
|
|||
---
|
||||
slug: guardrail-logging-secret-exposure-incident
|
||||
title: "Incident Report: Guardrail logging exposed secret headers in spend logs and traces"
|
||||
date: 2026-03-18T10:00:00
|
||||
authors:
|
||||
- litellm
|
||||
tags: [incident-report, security, guardrails]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
**Date:** March 18, 2026
|
||||
**Duration:** Unknown
|
||||
**Severity:** High
|
||||
**Status:** Resolved
|
||||
|
||||
## Summary
|
||||
|
||||
When a custom guardrail returned the full LiteLLM request/data dictionary, the guardrail response logged by LiteLLM could include `secret_fields.raw_headers`, including plaintext `Authorization` headers containing API keys or other credentials.
|
||||
|
||||
This information could then propagate to logging and observability surfaces that consume guardrail metadata, including:
|
||||
|
||||
- **Spend logs in the LiteLLM UI:** visible to admins with access to spend-log data
|
||||
- **OpenTelemetry traces:** visible to anyone with access to the relevant telemetry backend
|
||||
|
||||
LLM calls, proxy routing, and provider execution were not blocked by this bug. The impact was exposure of sensitive request headers in observability and logging paths.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
---
|
||||
|
||||
## Background
|
||||
|
||||
LiteLLM keeps internal request data (including request headers) for use during the call. That data is not meant to be written to logs or telemetry.
|
||||
|
||||
When custom guardrails run, their outcomes are logged so they can appear in spend logs, OpenTelemetry traces, and other observability backends. If a guardrail returned the full request payload instead of a minimal result, that internal request data could be included in what was logged. Before the fix, the guardrail logging path did not strip that data before sending it to those systems.
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
inboundRequest["1. Incoming proxy request"] --> storeSecrets["2. Store internal request data"]
|
||||
storeSecrets --> guardrailRuns["3. Custom guardrail runs"]
|
||||
guardrailRuns --> fullDataReturn["4. Guardrail returns full request payload"]
|
||||
fullDataReturn --> loggingBuild["5. Build guardrail log payload"]
|
||||
loggingBuild --> spendLogs["6a. Persist to spend logs / UI"]
|
||||
loggingBuild --> otelTraces["6b. Attach to OTEL guardrail spans"]
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Root Cause
|
||||
|
||||
The root cause was incomplete sanitization in the guardrail logging path. When building the payload that gets sent to spend logs and traces, LiteLLM prepared guardrail responses for logging but did not strip internal request data (such as headers) from them. If a guardrail returned a response that included that data, it was passed through to the logging and observability systems unchanged.
|
||||
|
||||
---
|
||||
|
||||
## Impact
|
||||
|
||||
This issue required all of the following:
|
||||
|
||||
1. A custom guardrail returned the full LiteLLM request/data dictionary, or another response object containing `secret_fields`.
|
||||
2. LiteLLM logged that guardrail response through the standard guardrail logging path.
|
||||
3. An operator, admin, or telemetry consumer had access to the resulting logs or traces.
|
||||
|
||||
When those conditions were met, sensitive values could become visible through:
|
||||
|
||||
- **Spend logs / UI responses:** guardrail metadata could be included in spend-log payloads rendered in the admin UI.
|
||||
- **OpenTelemetry traces:** `guardrail_response` could be written as a span attribute on guardrail spans.
|
||||
- **Other downstream observability backends:** any integration consuming the same guardrail metadata could receive the leaked values.
|
||||
|
||||
This was a logging and telemetry exposure bug. It did not let callers bypass auth, access other tenants directly, or change model behavior, but it could expose plaintext credentials to people with access to those observability systems.
|
||||
|
||||
---
|
||||
|
||||
## Guidance For Users
|
||||
|
||||
- Upgrade to LiteLLM 1.82.3+.
|
||||
- If you operated custom guardrails that return the full request/data dict, review whether spend logs or telemetry traces were retained during the affected period.
|
||||
- Rotate any credentials that may have appeared in `Authorization` or other forwarded request headers in those systems.
|
||||
- Apply least-privilege access controls to spend-log views and telemetry backends that may contain request-derived metadata.
|
||||
|
|
@ -1,126 +0,0 @@
|
|||
---
|
||||
slug: httpx-cache-eviction-incident
|
||||
title: "Incident Report: Cache Eviction Closes In-Use httpx Clients"
|
||||
date: 2026-02-27T10:00:00
|
||||
authors:
|
||||
- ryan
|
||||
- ishaan-alt
|
||||
- krrish
|
||||
tags: [incident-report, caching, stability]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
**Date:** February 27, 2026
|
||||
**Duration:** ~6 days (Feb 21 merge -> Feb 27 fix)
|
||||
**Severity:** High
|
||||
**Status:** Resolved
|
||||
|
||||
> **Note:** This fix is available starting from LiteLLM `v1.81.14.rc.2` or higher.
|
||||
|
||||
## Summary
|
||||
|
||||
A change to improve Redis connection pool cleanup introduced a regression that closed **httpx clients** that were still actively being used by the proxy. The `LLMClientCache` (an in-memory TTL cache) stores both Redis clients *and* httpx clients under the same eviction policy. When a cache entry expired or was evicted, the new cleanup code called `aclose()`/`close()` on the evicted value which worked correctly for Redis clients, but destroyed httpx clients that other parts of the system still held references to and were actively using for LLM API calls.
|
||||
|
||||
**Impact:** Any proxy instance that hit the cache TTL (default 10 minutes) or capacity limit (200 entries) would have its httpx clients closed out from under it, causing requests to LLM providers to fail with connection errors.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
---
|
||||
|
||||
## Background
|
||||
|
||||
`LLMClientCache` extends `InMemoryCache` and is used to cache SDK clients (OpenAI, Anthropic, etc.) to avoid re-creating them on every request. These clients are keyed by configuration + event loop ID. The cache has:
|
||||
|
||||
- **Max size:** 200 entries
|
||||
- **Default TTL:** 10 minutes
|
||||
|
||||
When the cache is full or entries expire, `InMemoryCache.evict_cache()` calls `_remove_key()` to drop entries.
|
||||
|
||||
The cached values are a mix of:
|
||||
- **Redis/async Redis clients** — owned exclusively by the cache, safe to close on eviction
|
||||
- **httpx-backed SDK clients** (OpenAI, Anthropic, etc.) — shared references, still in use by router/model instances
|
||||
|
||||
---
|
||||
|
||||
## Root Cause
|
||||
|
||||
[PR #21717](https://github.com/BerriAI/litellm/pull/21717) overrode `_remove_key()` in `LLMClientCache` to close async clients on eviction:
|
||||
|
||||
<details>
|
||||
<summary>Problematic code added in PR #21717</summary>
|
||||
|
||||
```python
|
||||
class LLMClientCache(InMemoryCache):
|
||||
def _remove_key(self, key: str) -> None:
|
||||
value = self.cache_dict.get(key)
|
||||
super()._remove_key(key)
|
||||
if value is not None:
|
||||
close_fn = getattr(value, "aclose", None) or getattr(value, "close", None)
|
||||
if close_fn and asyncio.iscoroutinefunction(close_fn):
|
||||
try:
|
||||
asyncio.get_running_loop().create_task(close_fn())
|
||||
except RuntimeError:
|
||||
pass
|
||||
elif close_fn and callable(close_fn):
|
||||
try:
|
||||
close_fn()
|
||||
except Exception:
|
||||
pass
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
The intent was correct for Redis clients — prevent connection pool leaks when cached Redis clients expire. But `LLMClientCache` also stores httpx-backed SDK clients (e.g., `AsyncOpenAI`, `AsyncAnthropic`). These clients:
|
||||
|
||||
1. Have an `aclose()` method (inherited from httpx)
|
||||
2. Are still held by references elsewhere in the codebase (router, model instances)
|
||||
3. Were being closed without any check on whether they were still in use
|
||||
|
||||
So when the cache evicted an entry, it would call `aclose()` on an httpx client that was still being used for active LLM requests → closed transport → connection errors.
|
||||
|
||||
---
|
||||
|
||||
## The Fix
|
||||
|
||||
[PR #22247](https://github.com/BerriAI/litellm/pull/22247) removed the `_remove_key` override entirely:
|
||||
|
||||
<details>
|
||||
<summary>The fix (PR #22247)</summary>
|
||||
|
||||
```diff
|
||||
class LLMClientCache(InMemoryCache):
|
||||
- def _remove_key(self, key: str) -> None:
|
||||
- """Close async clients before evicting them to prevent connection pool leaks."""
|
||||
- value = self.cache_dict.get(key)
|
||||
- super()._remove_key(key)
|
||||
- if value is not None:
|
||||
- close_fn = getattr(value, "aclose", None) or getattr(
|
||||
- value, "close", None
|
||||
- )
|
||||
- ...
|
||||
-
|
||||
def update_cache_key_with_event_loop(self, key):
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
The eviction now simply drops the reference and lets Python's GC handle cleanup, which is safe because:
|
||||
- httpx clients that are still referenced elsewhere stay alive
|
||||
- Unreferenced clients get cleaned up by GC naturally
|
||||
|
||||
The other improvements from PR #21717 were kept:
|
||||
- **`max_connections` respected for URL-based Redis configs**, previously silently dropped
|
||||
- **`disconnect()` now closes both sync and async Redis clients**, sync client was previously leaked
|
||||
- **Connection pool passthrough**, when a pool is provided with a URL config, it's used directly instead of creating a duplicate
|
||||
|
||||
---
|
||||
|
||||
## Remediation
|
||||
|
||||
| Action | Status | Code |
|
||||
|--------|--------|------|
|
||||
| Remove `_remove_key` override that closes shared clients on eviction | ✅ Done | [PR #22247](https://github.com/BerriAI/litellm/pull/22247) |
|
||||
| Add e2e test: evicted client still usable (capacity) | ✅ Done | [PR #22313](https://github.com/BerriAI/litellm/pull/22313) |
|
||||
| Add e2e test: expired client still usable (TTL) | ✅ Done | [PR #22313](https://github.com/BerriAI/litellm/pull/22313) |
|
||||
|
||||
The e2e tests go through `get_async_httpx_client()` the same code path the proxy uses in production and assert the client is still functional after eviction. These run in CI on every PR against `main`. If anyone modifies `LLMClientCache` eviction behavior, overrides `_remove_key`, or adds any form of client cleanup on eviction, these tests will fail regardless of the implementation approach.
|
||||
|
|
@ -1,128 +0,0 @@
|
|||
---
|
||||
slug: litellm-observatory
|
||||
title: "Improve release stability with 24 hour load tests"
|
||||
date: 2026-02-06T10:00:00
|
||||
authors:
|
||||
- alexsander
|
||||
- krrish
|
||||
- ishaan-alt
|
||||
description: "How we built a long-running, release-validation system to catch regressions before they reach users."
|
||||
tags: [testing, observability, reliability, releases]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
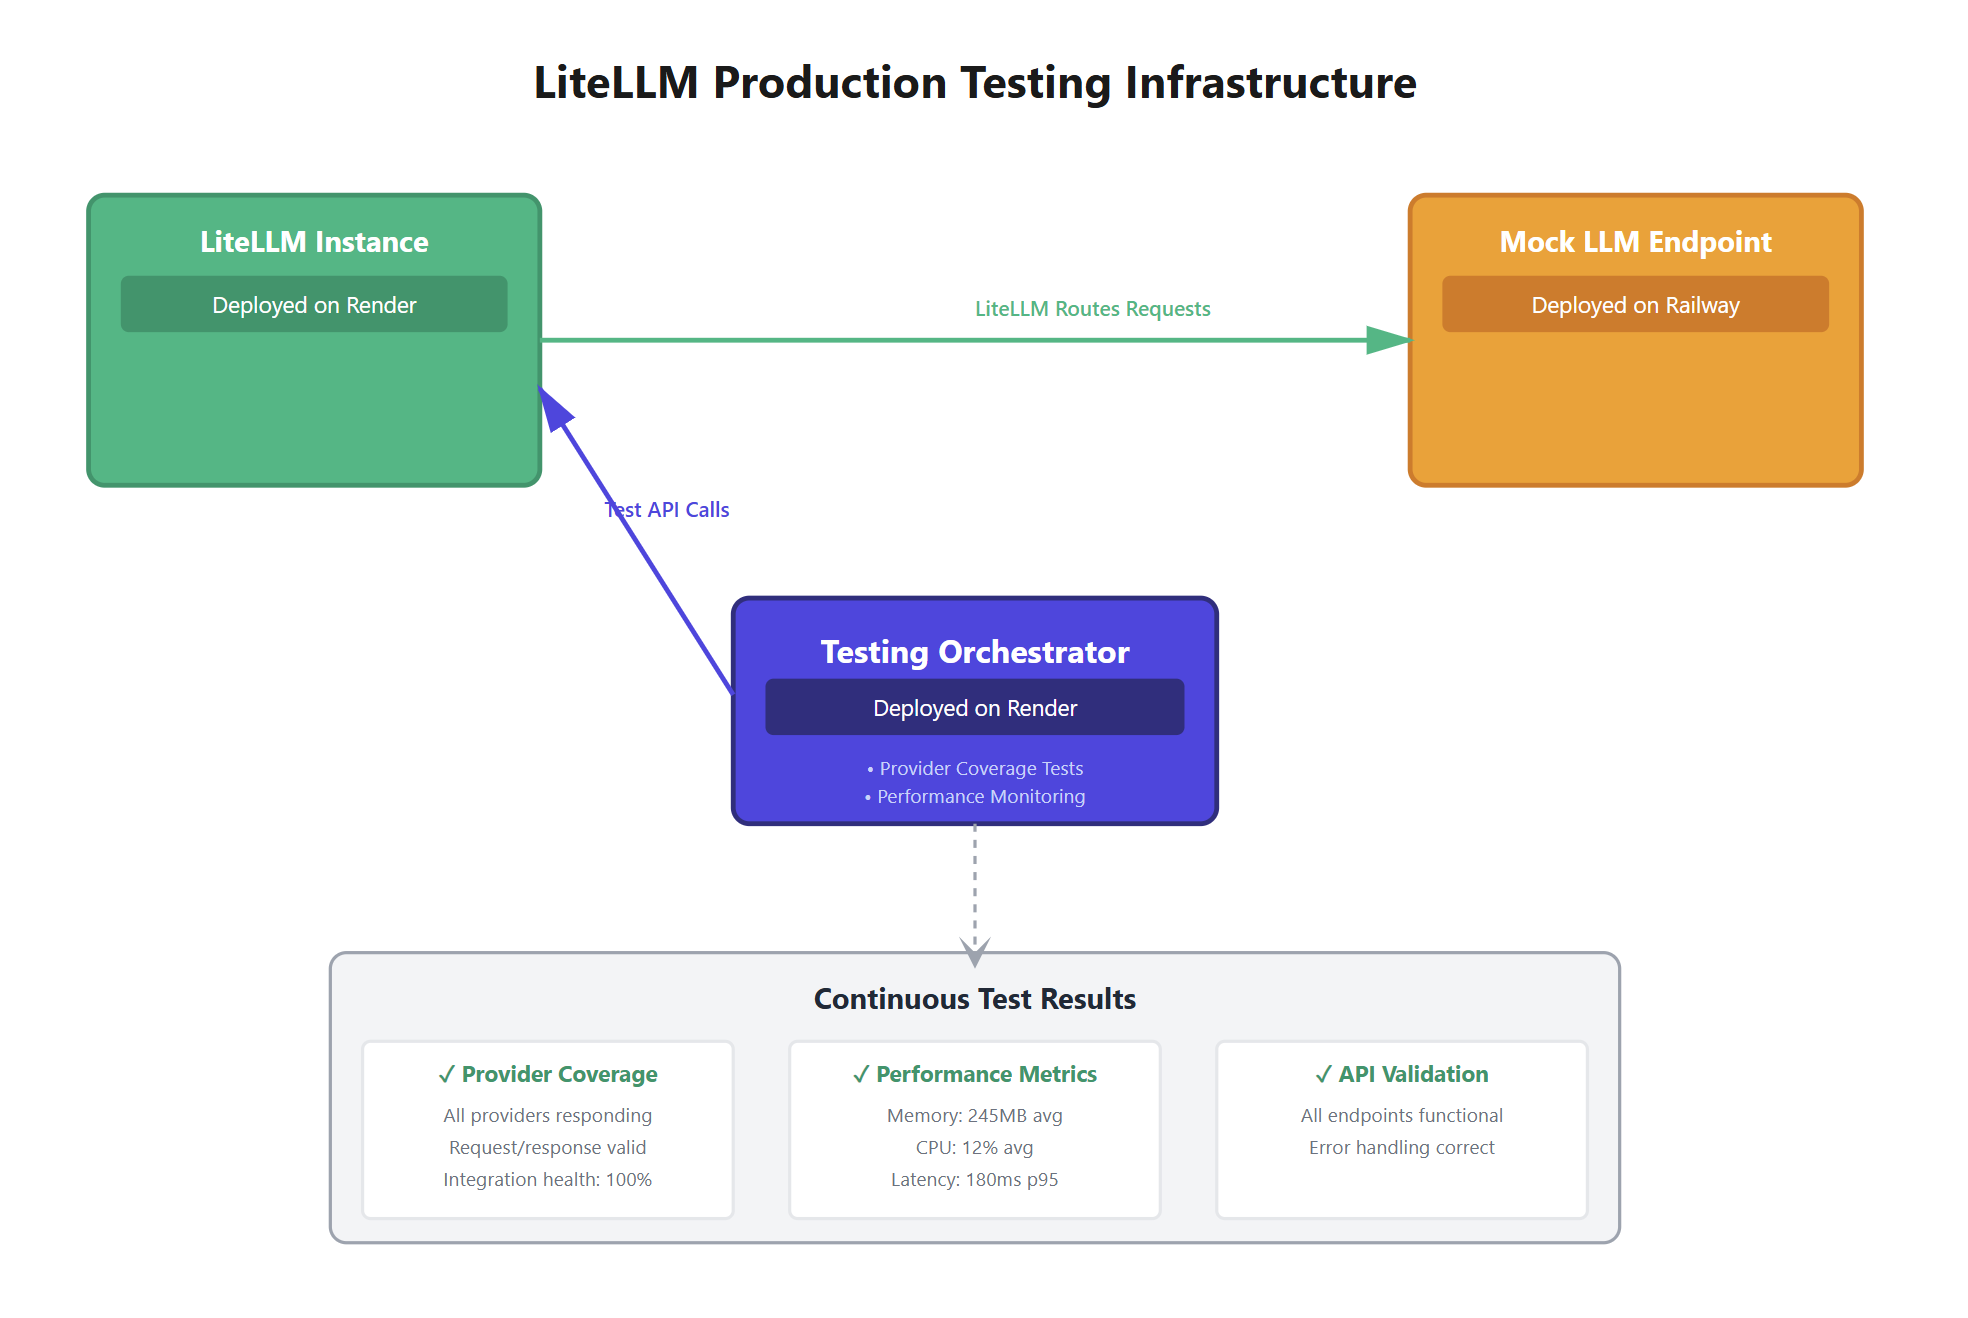
|
||||
|
||||
# Improve release stability with 24 hour load tests
|
||||
|
||||
As LiteLLM adoption has grown, so have expectations around reliability, performance, and operational safety. Meeting those expectations requires more than correctness-focused tests, it requires validating how the system behaves over time, under real-world conditions.
|
||||
|
||||
This post introduces **LiteLLM Observatory**, a long-running release-validation system we built to catch regressions before they reach users.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
---
|
||||
|
||||
## Why We Built the Observatory
|
||||
|
||||
LiteLLM operates at the intersection of external providers, long-lived network connections, and high-throughput workloads. While our unit and integration tests do an excellent job validating correctness, they are not designed to surface issues that only appear after extended operation.
|
||||
|
||||
A subtle lifecycle edge case discovered in v1.81.3 reinforced the need for stronger release validation in this area.
|
||||
|
||||
---
|
||||
|
||||
## A Real-World Lifecycle Edge Case
|
||||
|
||||
In v1.81.3, we shipped a fix for an HTTP client memory leak. The change passed unit and integration tests and behaved correctly in short-lived runs.
|
||||
|
||||
The issue that surfaced was not caused by a single incorrect line of logic, but by how multiple components interacted over time:
|
||||
|
||||
- A cached `httpx` client was configured with a 1-hour TTL
|
||||
- When the cache expired, the underlying HTTP connection was closed as expected
|
||||
- A higher-level client continued to hold a reference to that connection
|
||||
- Subsequent requests failed with:
|
||||
|
||||
```
|
||||
Cannot send a request, as the client has been closed
|
||||
```
|
||||
|
||||
**Before (with bug):**
|
||||
|
||||
| Provider | Requests | Success | Failures | Fail % |
|
||||
|----------|----------|---------|----------|--------|
|
||||
| OpenAI | 720,000 | 432,000 | 288,000 | 40% |
|
||||
| Azure | 692,000 | 415,200 | 276,800 | 40% |
|
||||
|
||||
**After (fixed):**
|
||||
|
||||
| Provider | Requests | Success | Failures | Fail % |
|
||||
|----------|------------|-----------|----------|---------|
|
||||
| OpenAI | 1,200,000 | 1,199,988 | 12 | 0.001% |
|
||||
| Azure | 1,150,000 | 1,149,982 | 18 | 0.002% |
|
||||
|
||||
Our focus moving forward is on being the first to detect issues, even when they aren’t covered by unit tests. LiteLLM Observatory is designed to surface latency regressions, OOMs, and failure modes that only appear under real traffic patterns in **our own production deployments** during release validation.
|
||||
|
||||
|
||||
---
|
||||
|
||||
### How the Observatory Works
|
||||
|
||||
[LiteLLM Observatory](https://github.com/BerriAI/litellm-observatory) is a testing service that runs long-running tests against our LiteLLM deployments. We trigger tests by sending API requests, and results are automatically sent to Slack when tests complete.
|
||||
|
||||
#### How Tests Run
|
||||
|
||||
1. **Start a Test**: We send a request to the Observatory API with:
|
||||
- Which LiteLLM deployment to test (URL and API key)
|
||||
- Which test to run (e.g., `TestOAIAzureRelease`)
|
||||
- Test settings (which models to test, how long to run, failure thresholds)
|
||||
|
||||
2. **Smart Queueing**:
|
||||
- The system checks whether we are attempting to run the exact same test more than once
|
||||
- If a duplicate test is already running or queued, we receive an error to avoid wasting resources
|
||||
- Otherwise, the test is added to a queue and runs when capacity is available (up to 5 tests can run concurrently by default)
|
||||
|
||||
3. **Instant Response**: The API responds immediately—we do not wait for the test to finish. Tests may run for hours, but the request itself completes in milliseconds.
|
||||
|
||||
4. **Background Execution**:
|
||||
- The test runs in the background, issuing requests against our LiteLLM deployment
|
||||
- It tracks request success and failure rates over time
|
||||
- When the test completes, results are automatically posted to our Slack channel
|
||||
|
||||
#### Example: The OpenAI / Azure Reliability Test
|
||||
|
||||
The `TestOAIAzureRelease` test is designed to catch a class of bugs that only surface after sustained runtime:
|
||||
|
||||
- **Duration**: Runs continuously for 3 hours
|
||||
- **Behavior**: Cycles through specified models (such as `gpt-4` and `gpt-3.5-turbo`), issuing requests continuously
|
||||
- **Why 3 Hours**: This helps catch issues where HTTP clients degrade or fail after extended use (for example, a bug observed in LiteLLM v1.81.3)
|
||||
- **Pass / Fail Criteria**: The test passes if fewer than 1% of requests fail. If the failure rate exceeds 1%, the test fails and we are notified in Slack
|
||||
- **Key Detail**: The same HTTP client is reused for the entire run, allowing us to detect lifecycle-related bugs that only appear under prolonged reuse
|
||||
|
||||
#### When We Use It
|
||||
|
||||
- **Before Deployments**: Run tests before promoting a new LiteLLM version to production
|
||||
- **Routine Validation**: Schedule regular runs (daily or weekly) to catch regressions early
|
||||
- **Issue Investigation**: Run tests on demand when we suspect a deployment issue
|
||||
- **Long-Running Failure Detection**: Identify bugs that only appear under sustained load, beyond what short smoke tests can reveal
|
||||
|
||||
|
||||
### Complementing Unit Tests
|
||||
|
||||
Unit tests remain a foundational part of our development process. They are fast and precise, but they don’t cover:
|
||||
|
||||
- Real provider behavior
|
||||
- Long-lived network interactions
|
||||
- Resource lifecycle edge cases
|
||||
- Time-dependent regressions
|
||||
|
||||
LiteLLM Observatory complements unit tests by validating the system as it actually runs in production-like environments.
|
||||
|
||||
---
|
||||
|
||||
### Looking Ahead
|
||||
|
||||
Reliability is an ongoing investment.
|
||||
|
||||
LiteLLM Observatory is one of several systems we’re building to continuously raise the bar on release quality and operational safety. As LiteLLM evolves, so will our validation tooling, informed by real-world usage and lessons learned.
|
||||
|
||||
We’ll continue to share those improvements openly as we go.
|
||||
|
|
@ -1,387 +0,0 @@
|
|||
---
|
||||
slug: minimax_m2_5
|
||||
title: "Day 0 Support: MiniMax-M2.5"
|
||||
date: 2026-02-12T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
- krrish
|
||||
- ishaan-alt
|
||||
description: "Day 0 support for MiniMax-M2.5 on LiteLLM"
|
||||
tags: [minimax, M2.5, llm]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
LiteLLM now supports MiniMax-M2.5 on Day 0. Use it across OpenAI-compatible and Anthropic-compatible APIs through the LiteLLM AI Gateway.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
## Supported Models
|
||||
|
||||
LiteLLM supports the following MiniMax models:
|
||||
|
||||
| Model | Description | Input Cost | Output Cost | Context Window |
|
||||
|-------|-------------|------------|-------------|----------------|
|
||||
| **MiniMax-M2.5** | Advanced reasoning, Agentic capabilities | $0.3/M tokens | $1.2/M tokens | 1M tokens |
|
||||
| **MiniMax-M2.5-lightning** | Faster and More Agile (~100 tps) | $0.3/M tokens | $2.4/M tokens | 1M tokens |
|
||||
|
||||
## Features Supported
|
||||
|
||||
- **Prompt Caching**: Reduce costs with cached prompts ($0.03/M tokens for cache read, $0.375/M tokens for cache write)
|
||||
- **Function Calling**: Built-in tool calling support
|
||||
- **Reasoning**: Advanced reasoning capabilities with thinking support
|
||||
- **System Messages**: Full system message support
|
||||
- **Cost Tracking**: Automatic cost calculation for all requests
|
||||
|
||||
## Docker Image
|
||||
|
||||
```bash
|
||||
docker pull litellm/litellm:v1.81.3-stable
|
||||
```
|
||||
|
||||
## Usage - OpenAI Compatible API (/v1/chat/completions)
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: minimax-m2-5
|
||||
litellm_params:
|
||||
model: minimax/MiniMax-M2.5
|
||||
api_key: os.environ/MINIMAX_API_KEY
|
||||
api_base: https://api.minimax.io/v1
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e MINIMAX_API_KEY=$MINIMAX_API_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:v1.81.3-stable \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "minimax-m2-5",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### With Reasoning Split
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "minimax-m2-5",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Solve: 2+2=?"
|
||||
}
|
||||
],
|
||||
"extra_body": {
|
||||
"reasoning_split": true
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
## Usage - Anthropic Compatible API (/v1/messages)
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: minimax-m2-5
|
||||
litellm_params:
|
||||
model: minimax/MiniMax-M2.5
|
||||
api_key: os.environ/MINIMAX_API_KEY
|
||||
api_base: https://api.minimax.io/anthropic/v1/messages
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e MINIMAX_API_KEY=$MINIMAX_API_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:v1.81.3-stable \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "minimax-m2-5",
|
||||
"max_tokens": 1000,
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### With Thinking
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "minimax-m2-5",
|
||||
"max_tokens": 1000,
|
||||
"thinking": {
|
||||
"type": "enabled",
|
||||
"budget_tokens": 1000
|
||||
},
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Solve: 2+2=?"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
## Usage - LiteLLM SDK
|
||||
|
||||
### OpenAI-compatible API
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[
|
||||
{"role": "user", "content": "Hello, how are you?"}
|
||||
],
|
||||
api_key="your-minimax-api-key",
|
||||
api_base="https://api.minimax.io/v1"
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
### Anthropic-compatible API
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.anthropic.messages.acreate(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[{"role": "user", "content": "Hello, how are you?"}],
|
||||
api_key="your-minimax-api-key",
|
||||
api_base="https://api.minimax.io/anthropic/v1/messages",
|
||||
max_tokens=1000
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
### With Thinking
|
||||
|
||||
```python
|
||||
response = litellm.anthropic.messages.acreate(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[{"role": "user", "content": "Solve: 2+2=?"}],
|
||||
thinking={"type": "enabled", "budget_tokens": 1000},
|
||||
api_key="your-minimax-api-key"
|
||||
)
|
||||
|
||||
# Access thinking content
|
||||
for block in response.choices[0].message.content:
|
||||
if hasattr(block, 'type') and block.type == 'thinking':
|
||||
print(f"Thinking: {block.thinking}")
|
||||
```
|
||||
|
||||
### With Reasoning Split (OpenAI API)
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[
|
||||
{"role": "user", "content": "Solve: 2+2=?"}
|
||||
],
|
||||
extra_body={"reasoning_split": True},
|
||||
api_key="your-minimax-api-key",
|
||||
api_base="https://api.minimax.io/v1"
|
||||
)
|
||||
|
||||
# Access thinking and response
|
||||
if hasattr(response.choices[0].message, 'reasoning_details'):
|
||||
print(f"Thinking: {response.choices[0].message.reasoning_details}")
|
||||
print(f"Response: {response.choices[0].message.content}")
|
||||
```
|
||||
|
||||
## Cost Tracking
|
||||
|
||||
LiteLLM automatically tracks costs for MiniMax-M2.5 requests. The pricing is:
|
||||
|
||||
- **Input**: $0.3 per 1M tokens
|
||||
- **Output**: $1.2 per 1M tokens
|
||||
- **Cache Read**: $0.03 per 1M tokens
|
||||
- **Cache Write**: $0.375 per 1M tokens
|
||||
|
||||
### Accessing Cost Information
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[{"role": "user", "content": "Hello!"}],
|
||||
api_key="your-minimax-api-key"
|
||||
)
|
||||
|
||||
# Access cost information
|
||||
print(f"Cost: ${response._hidden_params.get('response_cost', 0)}")
|
||||
```
|
||||
|
||||
## Streaming Support
|
||||
|
||||
### OpenAI API
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[{"role": "user", "content": "Tell me a story"}],
|
||||
stream=True,
|
||||
api_key="your-minimax-api-key",
|
||||
api_base="https://api.minimax.io/v1"
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
if chunk.choices[0].delta.content:
|
||||
print(chunk.choices[0].delta.content, end="")
|
||||
```
|
||||
|
||||
### Streaming with Reasoning Split
|
||||
|
||||
```python
|
||||
stream = litellm.completion(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[
|
||||
{"role": "user", "content": "Tell me a story"},
|
||||
],
|
||||
extra_body={"reasoning_split": True},
|
||||
stream=True,
|
||||
api_key="your-minimax-api-key",
|
||||
api_base="https://api.minimax.io/v1"
|
||||
)
|
||||
|
||||
reasoning_buffer = ""
|
||||
text_buffer = ""
|
||||
|
||||
for chunk in stream:
|
||||
if hasattr(chunk.choices[0].delta, "reasoning_details") and chunk.choices[0].delta.reasoning_details:
|
||||
for detail in chunk.choices[0].delta.reasoning_details:
|
||||
if "text" in detail:
|
||||
reasoning_text = detail["text"]
|
||||
new_reasoning = reasoning_text[len(reasoning_buffer):]
|
||||
if new_reasoning:
|
||||
print(new_reasoning, end="", flush=True)
|
||||
reasoning_buffer = reasoning_text
|
||||
|
||||
if chunk.choices[0].delta.content:
|
||||
content_text = chunk.choices[0].delta.content
|
||||
new_text = content_text[len(text_buffer):] if text_buffer else content_text
|
||||
if new_text:
|
||||
print(new_text, end="", flush=True)
|
||||
text_buffer = content_text
|
||||
```
|
||||
|
||||
## Using with Native SDKs
|
||||
|
||||
### Anthropic SDK via LiteLLM Proxy
|
||||
|
||||
```python
|
||||
import os
|
||||
os.environ["ANTHROPIC_BASE_URL"] = "http://localhost:4000"
|
||||
os.environ["ANTHROPIC_API_KEY"] = "sk-1234" # Your LiteLLM proxy key
|
||||
|
||||
import anthropic
|
||||
|
||||
client = anthropic.Anthropic()
|
||||
|
||||
message = client.messages.create(
|
||||
model="minimax-m2-5",
|
||||
max_tokens=1000,
|
||||
system="You are a helpful assistant.",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "text",
|
||||
"text": "Hi, how are you?"
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
)
|
||||
|
||||
for block in message.content:
|
||||
if block.type == "thinking":
|
||||
print(f"Thinking:\n{block.thinking}\n")
|
||||
elif block.type == "text":
|
||||
print(f"Text:\n{block.text}\n")
|
||||
```
|
||||
|
||||
### OpenAI SDK via LiteLLM Proxy
|
||||
|
||||
```python
|
||||
import os
|
||||
os.environ["OPENAI_BASE_URL"] = "http://localhost:4000"
|
||||
os.environ["OPENAI_API_KEY"] = "sk-1234" # Your LiteLLM proxy key
|
||||
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI()
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="minimax-m2-5",
|
||||
messages=[
|
||||
{"role": "system", "content": "You are a helpful assistant."},
|
||||
{"role": "user", "content": "Hi, how are you?"},
|
||||
],
|
||||
extra_body={"reasoning_split": True},
|
||||
)
|
||||
|
||||
# Access thinking and response
|
||||
if hasattr(response.choices[0].message, 'reasoning_details'):
|
||||
print(f"Thinking:\n{response.choices[0].message.reasoning_details[0]['text']}\n")
|
||||
print(f"Text:\n{response.choices[0].message.content}\n")
|
||||
```
|
||||
|
|
@ -1,92 +0,0 @@
|
|||
---
|
||||
slug: model-cost-map-incident
|
||||
title: "Incident Report: Invalid model cost map on main"
|
||||
date: 2026-02-10T10:00:00
|
||||
authors:
|
||||
- ishaan
|
||||
tags: [incident-report, stability]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
**Date:** January 27, 2026
|
||||
**Duration:** ~20 minutes
|
||||
**Severity:** Low
|
||||
**Status:** Resolved
|
||||
|
||||
## Summary
|
||||
|
||||
A malformed JSON entry in `model_prices_and_context_window.json` was merged to `main` ([`562f0a0`](https://github.com/BerriAI/litellm/commit/562f0a028251750e3d75386bee0e630d9796d0df)). This caused LiteLLM to silently fall back to a stale local copy of the model cost map. Users on older package versions lost cost tracking for newer models only (e.g. `azure/gpt-5.2`). No LLM calls were blocked.
|
||||
|
||||
- **LLM calls and proxy routing:** No impact.
|
||||
- **Cost tracking:** Impacted for newer models not present in the local backup. Older models were unaffected. The incident lasted ~20 minutes until the commit was reverted.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
---
|
||||
|
||||
## Background
|
||||
|
||||
The model cost map is not in the request path. It is used after the LLM response comes back, inside a try/catch, to calculate spend. A missing entry never blocks a call.
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
A["1. litellm.completion() receives request
|
||||
litellm/main.py"] --> B["2. Route to provider
|
||||
litellm/litellm_core_utils/get_llm_provider_logic.py"]
|
||||
B --> C["3. LLM returns response
|
||||
litellm/main.py"]
|
||||
C --> D["4. Post-call: look up model in cost map
|
||||
litellm/cost_calculator.py"]
|
||||
D -->|"found"| E["5a. Attach cost to response"]
|
||||
D -->|"not found (try/catch)"| F["5b. Log warning, set cost=0"]
|
||||
E --> G["6. Return response to caller"]
|
||||
F --> G
|
||||
|
||||
style D fill:#fff3cd,stroke:#ffc107
|
||||
style F fill:#fff3cd,stroke:#ffc107
|
||||
style E fill:#d4edda,stroke:#28a745
|
||||
style G fill:#d4edda,stroke:#28a745
|
||||
```
|
||||
|
||||
Both paths return a response to the caller. When the cost map lookup fails, the only difference is `cost=0` on that request.
|
||||
|
||||
---
|
||||
|
||||
## Root cause
|
||||
|
||||
LiteLLM fetches the model cost map from GitHub `main` at import time. If the fetch fails, it falls back to a local backup bundled with the package. Before this incident, the fallback was completely silent -- no warning was logged.
|
||||
|
||||
A contributor PR introduced an extra `{` bracket, producing invalid JSON. The remote fetch failed with `JSONDecodeError`, triggering the silent fallback. Users on older package versions had backup files missing newer models.
|
||||
|
||||
**Timeline:**
|
||||
|
||||
1. Malformed JSON merged to `main`
|
||||
2. LiteLLM installations fall back to local backup on next import
|
||||
3. Users report `"This model isn't mapped yet"` for newer models
|
||||
4. Bad commit identified and reverted (~20 minutes)
|
||||
|
||||
---
|
||||
|
||||
## Remediation
|
||||
|
||||
| # | Action | Status | Code |
|
||||
|---|---|---|---|
|
||||
| 1 | CI validation on `model_prices_and_context_window.json` | ✅ Done | [`test-model-map.yaml`](https://github.com/BerriAI/litellm/blob/main/.github/workflows/test-model-map.yaml) |
|
||||
| 2 | Warning log on fallback to local backup | ✅ Done | [`get_model_cost_map.py#L57-L68`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm_core_utils/get_model_cost_map.py#L57-L68) |
|
||||
| 3 | `GetModelCostMap` class with integrity validation helpers | ✅ Done | [`get_model_cost_map.py#L24-L149`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm_core_utils/get_model_cost_map.py#L24-L149) |
|
||||
| 4 | Resilience test suite (bad hosted map, fallback, completion) | ✅ Done | [`test_model_cost_map_resilience.py#L150-L291`](https://github.com/BerriAI/litellm/blob/main/tests/llm_translation/test_model_cost_map_resilience.py#L150-L291) |
|
||||
| 5 | Test that backup model cost map always exists and contains common models | ✅ Done | [`test_model_cost_map_resilience.py#L213-L228`](https://github.com/BerriAI/litellm/blob/main/tests/llm_translation/test_model_cost_map_resilience.py#L213-L228) |
|
||||
|
||||
Enterprises that require zero external dependencies at import time can set `LITELLM_LOCAL_MODEL_COST_MAP=True` to skip the GitHub fetch entirely.
|
||||
|
||||
---
|
||||
|
||||
## Other dependencies on external resources
|
||||
|
||||
| Dependency | Impact if unavailable | Fallback |
|
||||
|---|---|---|
|
||||
| Model cost map (GitHub) | Cost tracking for newer models | Local backup (now with warning) |
|
||||
| JWT public keys (IDP/SSO) | Auth fails | None |
|
||||
| OIDC UserInfo (IDP/SSO) | Auth fails | None |
|
||||
| HuggingFace model API | HF provider calls fail | None |
|
||||
| Ollama tags (localhost) | Ollama model list stale | Static list |
|
||||
|
|
@ -1,111 +0,0 @@
|
|||
---
|
||||
slug: realtime_webrtc_http_endpoints
|
||||
title: "Realtime WebRTC HTTP Endpoints"
|
||||
date: 2026-03-12T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
- krrish
|
||||
- ishaan-alt
|
||||
description: "Use the LiteLLM proxy to route OpenAI-style WebRTC realtime via HTTP: client_secrets and SDP exchange."
|
||||
tags: [realtime, webrtc, proxy, openai]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import WebRTCTester from '@site/src/components/WebRTCTester';
|
||||
|
||||
Connect to the Realtime API via WebRTC from browser/mobile clients. LiteLLM handles auth and key management.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
## How it works
|
||||
|
||||

|
||||
|
||||
**Flow of generating ephemeral token**
|
||||
|
||||

|
||||
|
||||
|
||||
## Proxy Setup
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-4o-realtime
|
||||
litellm_params:
|
||||
model: openai/gpt-4o-realtime-preview-2024-12-17
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
```
|
||||
|
||||
**Azure:** use `model: azure/gpt-4o-realtime-preview`, `api_key`, `api_base`.
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
## Try it live
|
||||
|
||||
<WebRTCTester />
|
||||
|
||||
## Client Usage
|
||||
|
||||
**1. Get token** - `POST /v1/realtime/client_secrets` with LiteLLM API key and `{ model }`.
|
||||
|
||||
**2. WebRTC handshake** - Create `RTCPeerConnection`, add mic track, create data channel `oai-events`, send SDP offer to `POST /v1/realtime/calls` with `Authorization: Bearer <encrypted_token>` and `Content-Type: application/sdp`.
|
||||
|
||||
**3. Events** - Use the data channel for `session.update` and other events.
|
||||
|
||||
<details>
|
||||
<summary>Full code example</summary>
|
||||
|
||||
```javascript
|
||||
// 1. Token
|
||||
const r = await fetch("http://proxy:4000/v1/realtime/client_secrets", {
|
||||
method: "POST",
|
||||
headers: { "Authorization": "Bearer sk-litellm-key", "Content-Type": "application/json" },
|
||||
body: JSON.stringify({ model: "gpt-4o-realtime" }),
|
||||
});
|
||||
const { client_secret } = await r.json();
|
||||
const token = client_secret.value;
|
||||
|
||||
// 2. WebRTC
|
||||
const pc = new RTCPeerConnection();
|
||||
const audio = document.createElement("audio");
|
||||
audio.autoplay = true;
|
||||
pc.ontrack = (e) => (audio.srcObject = e.streams[0]);
|
||||
const ms = await navigator.mediaDevices.getUserMedia({ audio: true });
|
||||
pc.addTrack(ms.getTracks()[0]);
|
||||
const dc = pc.createDataChannel("oai-events");
|
||||
const offer = await pc.createOffer();
|
||||
await pc.setLocalDescription(offer);
|
||||
|
||||
const sdpRes = await fetch("http://proxy:4000/v1/realtime/calls", {
|
||||
method: "POST",
|
||||
headers: { "Authorization": `Bearer ${token}`, "Content-Type": "application/sdp" },
|
||||
body: offer.sdp,
|
||||
});
|
||||
await pc.setRemoteDescription({ type: "answer", sdp: await sdpRes.text() });
|
||||
|
||||
// 3. Events
|
||||
dc.send(JSON.stringify({ type: "session.update", session: { instructions: "..." } }));
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
## FAQ
|
||||
|
||||
**Q: What do I do if I get a 401 Token expired error?**
|
||||
A: Tokens are short-lived. Get a fresh token right before creating the WebRTC offer.
|
||||
|
||||
**Q: Which key should I use for `/v1/realtime/calls`?**
|
||||
A: Use the **encrypted token** from `client_secrets`, not your raw API key.
|
||||
|
||||
**Q: Should I pass the `model` parameter when making the call?**
|
||||
A: No, the encrypted token already encodes all routing information including model.
|
||||
|
||||
**Q: How do I resolve Azure `api-version` errors?**
|
||||
A: Set the correct `api_version` in `litellm_params` (or via the `AZURE_API_VERSION` environment variable), along with the right `api_base` and deployment values.
|
||||
|
||||
**Q: What if I get no audio?**
|
||||
A: Make sure you grant microphone permission, ensure `pc.ontrack` assigns the audio element with `autoplay` enabled, check your network/firewall for WebRTC traffic, and inspect the browser console for ICE or SDP errors.
|
||||
|
|
@ -1,312 +0,0 @@
|
|||
---
|
||||
slug: responses-api-encrypted-content-incident
|
||||
title: "Incident Report: Encrypted Content Failures in Multi-Region Responses API Load Balancing"
|
||||
date: 2026-02-24T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
- krrish
|
||||
- ishaan-alt
|
||||
tags: [incident-report, proxy, responses-api, load-balancing]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
**Date:** Feb 24, 2026
|
||||
**Duration:** Ongoing (until fix deployed)
|
||||
**Severity:** High (for users load balancing Responses API across different API keys)
|
||||
**Status:** Resolved
|
||||
|
||||
## Summary
|
||||
|
||||
When load balancing OpenAI's Responses API across deployments with **different API keys** (e.g., different Azure regions or OpenAI organizations), follow-up requests containing encrypted content items (like `rs_...` reasoning items) would fail with:
|
||||
|
||||
```json
|
||||
{
|
||||
"error": {
|
||||
"message": "The encrypted content for item rs_0d09d6e56879e76500699d6feee41c8197bd268aae76141f87 could not be verified. Reason: Encrypted content organization_id did not match the target organization.",
|
||||
"type": "invalid_request_error",
|
||||
"code": "invalid_encrypted_content"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Encrypted content items are cryptographically tied to the API key's organization that created them. When the router load balanced a follow-up request to a deployment with a different API key, decryption failed.
|
||||
|
||||
- **Responses API calls with encrypted content:** Complete failure when routed to wrong deployment
|
||||
- **Initial requests:** Unaffected — only follow-up requests containing encrypted items failed
|
||||
- **Other API endpoints:** No impact — chat completions, embeddings, etc. functioned normally
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
---
|
||||
|
||||
## Background
|
||||
|
||||
OpenAI's Responses API can return encrypted "reasoning items" (with IDs like `rs_...`) that contain intermediate reasoning steps. These items are encrypted with the organization's key and can only be decrypted by the same organization's API key.
|
||||
|
||||
When load balancing across deployments with different API keys, the existing affinity mechanisms were insufficient:
|
||||
|
||||
- **`responses_api_deployment_check`**: Requires `previous_response_id` which some clients (like Codex) don't provide
|
||||
- **`deployment_affinity`**: Too broad — pins *all* requests from a user to one deployment, reducing effective quota by the number of users
|
||||
- **`session_affinity`**: Requires explicit session IDs and still reduces quota
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
A["1. Initial request to Responses API
|
||||
router.aresponses()"] --> B["2. Router load balances to Deployment A
|
||||
(API Key 1, Azure East US)"]
|
||||
B --> C["3. Response contains encrypted item
|
||||
rs_abc123 (encrypted with Org 1 key)"]
|
||||
C --> D["4. Follow-up request includes rs_abc123 in input"]
|
||||
D --> E["5. Router load balances to Deployment B
|
||||
(API Key 2, Azure West Europe)"]
|
||||
E -->|"Different API key"| F["6. ❌ Deployment B cannot decrypt rs_abc123
|
||||
Error: invalid_encrypted_content"]
|
||||
|
||||
D -.->|"With encrypted_content_affinity"| G["5b. Router detects rs_abc123 was created by Deployment A"]
|
||||
G --> H["6b. ✅ Routes to Deployment A (bypasses rate limits)
|
||||
Request succeeds"]
|
||||
|
||||
style F fill:#f8d7da,stroke:#dc3545
|
||||
style H fill:#d4edda,stroke:#28a745
|
||||
style E fill:#fff3cd,stroke:#ffc107
|
||||
style G fill:#d4edda,stroke:#28a745
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Root Cause
|
||||
|
||||
LiteLLM's router had no mechanism to track which deployment created specific encrypted content items and route follow-up requests accordingly. The router treated all deployments as interchangeable, leading to decryption failures when encrypted content crossed organizational boundaries.
|
||||
|
||||
**The Problem Flow:**
|
||||
|
||||
1. User calls `router.aresponses()` with model `gpt-5.1-codex`
|
||||
2. Router load balances to Deployment A (Azure East US, API Key 1)
|
||||
3. Response contains encrypted reasoning item `rs_abc123` (encrypted with Org 1's key)
|
||||
4. User makes follow-up request with `rs_abc123` in the input
|
||||
5. Router load balances to Deployment B (Azure West Europe, API Key 2)
|
||||
6. Deployment B tries to decrypt `rs_abc123` with Org 2's key → **fails**
|
||||
|
||||
**Why Existing Solutions Didn't Work:**
|
||||
|
||||
- **`previous_response_id`**: Not provided by all clients (e.g., Codex)
|
||||
- **`deployment_affinity`**: Pins *all* user requests to one deployment → reduces quota to 1/N where N = number of deployments
|
||||
- **`session_affinity`**: Requires explicit session management and still reduces quota
|
||||
|
||||
**Timeline:**
|
||||
|
||||
1. Users configured multi-region Responses API load balancing with different API keys
|
||||
2. Initial requests succeeded, but follow-up requests with encrypted content failed intermittently
|
||||
3. Error rate correlated with number of deployments (more deployments = higher chance of routing to wrong one)
|
||||
4. Investigation revealed encrypted content was organization-bound
|
||||
5. Existing affinity mechanisms deemed unsuitable (quota reduction, missing `previous_response_id`)
|
||||
6. New solution designed and implemented: `encrypted_content_affinity`
|
||||
|
||||
---
|
||||
|
||||
## The Fix
|
||||
|
||||
Implemented a new `encrypted_content_affinity` pre-call check that intelligently tracks encrypted content and routes follow-up requests **only when necessary**.
|
||||
|
||||
### Implementation
|
||||
|
||||
**1. Encoding `model_id` into output items** ([`responses/utils.py`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm/responses/utils.py))
|
||||
|
||||
The same approach used for `previous_response_id` affinity — no cache needed. When a response contains output items with `encrypted_content`, LiteLLM encodes the originating deployment's `model_id` in **two places** for redundancy:
|
||||
|
||||
1. **Into the item ID** (if present): `rs_abc123` → `encitem_{base64("litellm:model_id:{model_id};item_id:rs_abc123")}`
|
||||
2. **Into the encrypted_content itself**: Wraps the content with `litellm_enc:{base64("model_id:{model_id}")};{original_encrypted_content}`
|
||||
|
||||
```python
|
||||
# Encoding item IDs (when present)
|
||||
def _build_encrypted_item_id(model_id: str, item_id: str) -> str:
|
||||
assembled = f"litellm:model_id:{model_id};item_id:{item_id}"
|
||||
encoded = base64.b64encode(assembled.encode("utf-8")).decode("utf-8")
|
||||
return f"encitem_{encoded}"
|
||||
|
||||
# Wrapping encrypted_content (always, for redundancy)
|
||||
def _wrap_encrypted_content_with_model_id(encrypted_content: str, model_id: str) -> str:
|
||||
metadata = f"model_id:{model_id}"
|
||||
encoded_metadata = base64.b64encode(metadata.encode("utf-8")).decode("utf-8")
|
||||
return f"litellm_enc:{encoded_metadata};{encrypted_content}"
|
||||
```
|
||||
|
||||
**Why wrap encrypted_content directly?** Some clients (like Codex) don't consistently send item IDs in follow-up requests, but they always send the `encrypted_content` itself. By embedding `model_id` into the content, affinity works even when IDs are missing.
|
||||
|
||||
**Streaming responses:** The wrapping logic is applied to both:
|
||||
- Final response objects (non-streaming)
|
||||
- Individual streaming events (`response.output_item.added`, `response.output_item.done`)
|
||||
|
||||
This ensures clients receiving streaming responses get wrapped content they can send back.
|
||||
|
||||
Before forwarding to the upstream provider, LiteLLM restores the original item IDs and unwraps encrypted_content so the provider never sees the encoded form:
|
||||
|
||||
```python
|
||||
# In responses/main.py — before calling the handler
|
||||
input = ResponsesAPIRequestUtils._restore_encrypted_content_item_ids_in_input(input)
|
||||
```
|
||||
|
||||
**2. `EncryptedContentAffinityCheck` — routing only** ([`encrypted_content_affinity_check.py`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm/router_utils/pre_call_checks/encrypted_content_affinity_check.py))
|
||||
|
||||
No `async_log_success_event` or cache lookups — the `model_id` is decoded directly from the item ID or encrypted_content:
|
||||
|
||||
```python
|
||||
class EncryptedContentAffinityCheck(CustomLogger):
|
||||
async def async_filter_deployments(self, model, healthy_deployments, ...):
|
||||
"""Extract model_id from input items (ID or encrypted_content) and pin to that deployment."""
|
||||
for item in request_kwargs.get("input", []):
|
||||
# Try to extract model_id from two sources:
|
||||
model_id = self._extract_model_id_from_input(item)
|
||||
|
||||
if model_id:
|
||||
deployment = self._find_deployment_by_model_id(
|
||||
healthy_deployments, model_id
|
||||
)
|
||||
if deployment:
|
||||
request_kwargs["_encrypted_content_affinity_pinned"] = True
|
||||
return [deployment]
|
||||
return healthy_deployments
|
||||
|
||||
def _extract_model_id_from_input(self, item: dict) -> Optional[str]:
|
||||
"""Extract model_id from either encoded ID or wrapped encrypted_content."""
|
||||
# 1. Try decoding from item ID (if present)
|
||||
item_id = item.get("id", "")
|
||||
if item_id:
|
||||
decoded = ResponsesAPIRequestUtils._decode_encrypted_item_id(item_id)
|
||||
if decoded:
|
||||
return decoded["model_id"]
|
||||
|
||||
# 2. Try unwrapping from encrypted_content (fallback for clients that omit IDs)
|
||||
encrypted_content = item.get("encrypted_content", "")
|
||||
if encrypted_content and encrypted_content.startswith("litellm_enc:"):
|
||||
model_id, _ = ResponsesAPIRequestUtils._unwrap_encrypted_content_with_model_id(
|
||||
encrypted_content
|
||||
)
|
||||
return model_id
|
||||
|
||||
return None
|
||||
```
|
||||
|
||||
**3. Rate Limit Bypass** ([`router.py`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm/router.py))
|
||||
|
||||
When encrypted content requires a specific deployment, RPM/TPM limits are bypassed (the request would fail on any other deployment anyway):
|
||||
|
||||
```python
|
||||
# In async_get_available_deployment, after filtering healthy deployments:
|
||||
if (
|
||||
request_kwargs.get("_encrypted_content_affinity_pinned")
|
||||
and len(healthy_deployments) == 1
|
||||
):
|
||||
return healthy_deployments[0] # Bypass routing strategy (RPM/TPM checks)
|
||||
```
|
||||
|
||||
**3. Configuration**
|
||||
|
||||
```yaml
|
||||
router_settings:
|
||||
routing_strategy: usage-based-routing-v2
|
||||
enable_pre_call_checks: true
|
||||
optional_pre_call_checks:
|
||||
- encrypted_content_affinity
|
||||
deployment_affinity_ttl_seconds: 86400 # 24 hours
|
||||
```
|
||||
|
||||
### Key Benefits
|
||||
|
||||
✅ **No quota reduction**: Only pins requests containing encrypted items
|
||||
✅ **Bypasses rate limits**: When encrypted content requires a specific deployment, RPM/TPM limits don't block it
|
||||
✅ **No `previous_response_id` required**: Works by encoding `model_id` directly into the item ID
|
||||
✅ **No cache required**: `model_id` is decoded on-the-fly from the item ID — no Redis, no TTL
|
||||
✅ **Globally safe**: Can be enabled for all models; non-Responses-API calls are unaffected
|
||||
✅ **Surgical precision**: Normal requests continue to load balance freely
|
||||
|
||||
---
|
||||
|
||||
## Remediation
|
||||
|
||||
| # | Action | Status | Code |
|
||||
|---|---|---|---|
|
||||
| 1 | Encode `model_id` into encrypted-content item IDs on response | ✅ Done | [`responses/utils.py`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm/responses/utils.py) |
|
||||
| 2 | Restore original item IDs before forwarding to upstream provider | ✅ Done | [`responses/main.py`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm/responses/main.py) |
|
||||
| 3 | `EncryptedContentAffinityCheck`: decode item IDs to route (no cache) | ✅ Done | [`encrypted_content_affinity_check.py`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm/router_utils/pre_call_checks/encrypted_content_affinity_check.py) |
|
||||
| 4 | Add `encrypted_content_affinity` to `OptionalPreCallChecks` type | ✅ Done | [`types/router.py`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm/types/router.py) |
|
||||
| 5 | Implement rate limit bypass for affinity-pinned requests | ✅ Done | [`router.py`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm/router.py) |
|
||||
| 6 | Unit tests: encoding/decoding utilities, routing, RPM bypass | ✅ Done | [`test_encrypted_content_affinity_check.py`](https://github.com/BerriAI/litellm/blob/main/litellm/tests/test_litellm/router_utils/pre_call_checks/test_encrypted_content_affinity_check.py) |
|
||||
| 7 | Documentation: Responses API guide, load balancing guide, config reference | ✅ Done | [Docs](https://docs.litellm.ai/docs/response_api#encrypted-content-affinity-multi-region-load-balancing) |
|
||||
| 8 | **[Mar 3]** Fix streaming events to wrap encrypted_content | ✅ Done | [`responses/streaming_iterator.py`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm/responses/streaming_iterator.py) |
|
||||
|
||||
---
|
||||
|
||||
## Follow-up Fix: Streaming Responses (Mar 3, 2026)
|
||||
|
||||
### The Issue
|
||||
|
||||
After the initial fix was deployed, users reported that the `invalid_encrypted_content` error **still occurred** when using streaming responses with clients like Codex. Investigation revealed:
|
||||
|
||||
- ✅ Non-streaming responses: `encrypted_content` was correctly wrapped with `litellm_enc:` prefix
|
||||
- ❌ Streaming responses: Individual `response.output_item.added` and `response.output_item.done` events contained **raw, unwrapped** `encrypted_content`
|
||||
|
||||
Since Codex and other clients consume responses as streams, they received unwrapped content in these events and sent it back in follow-up requests, causing the affinity check to fail.
|
||||
|
||||
### The Root Cause
|
||||
|
||||
The `_update_encrypted_content_item_ids_in_response` function only modified the **final** response object, which is used for non-streaming responses. For streaming responses, individual chunks are processed by `ResponsesAPIStreamingIterator._process_chunk`, which was **not** applying the wrapping logic to streaming events.
|
||||
|
||||
### The Fix
|
||||
|
||||
Modified `litellm/litellm/responses/streaming_iterator.py` to wrap `encrypted_content` in streaming events:
|
||||
|
||||
```python
|
||||
# In ResponsesAPIStreamingIterator._process_chunk
|
||||
if (
|
||||
self.litellm_metadata
|
||||
and self.litellm_metadata.get("encrypted_content_affinity_enabled")
|
||||
):
|
||||
event_type = getattr(openai_responses_api_chunk, "type", None)
|
||||
if event_type in (
|
||||
ResponsesAPIStreamEvents.OUTPUT_ITEM_ADDED,
|
||||
ResponsesAPIStreamEvents.OUTPUT_ITEM_DONE,
|
||||
):
|
||||
item = getattr(openai_responses_api_chunk, "item", None)
|
||||
if item:
|
||||
encrypted_content = getattr(item, "encrypted_content", None)
|
||||
if encrypted_content and isinstance(encrypted_content, str):
|
||||
model_id = (
|
||||
self.litellm_metadata.get("model_info", {}).get("id")
|
||||
if self.litellm_metadata
|
||||
else None
|
||||
)
|
||||
if model_id:
|
||||
wrapped_content = ResponsesAPIRequestUtils._wrap_encrypted_content_with_model_id(
|
||||
encrypted_content, model_id
|
||||
)
|
||||
setattr(item, "encrypted_content", wrapped_content)
|
||||
```
|
||||
|
||||
This ensures that **all** `encrypted_content` sent to clients (streaming or non-streaming) is wrapped with `model_id` metadata, enabling consistent affinity routing.
|
||||
|
||||
---
|
||||
|
||||
## Migration Guide
|
||||
|
||||
### Before (Using `deployment_affinity`)
|
||||
|
||||
```yaml
|
||||
router_settings:
|
||||
optional_pre_call_checks:
|
||||
- deployment_affinity # ❌ Reduces quota by number of users
|
||||
```
|
||||
|
||||
**Problem:** All requests from a user pin to one deployment, reducing effective quota to 1/N.
|
||||
|
||||
### After (Using `encrypted_content_affinity`)
|
||||
|
||||
```yaml
|
||||
router_settings:
|
||||
optional_pre_call_checks:
|
||||
- encrypted_content_affinity # ✅ Only pins requests with encrypted content
|
||||
```
|
||||
|
||||
**Benefit:** Normal requests load balance freely, only encrypted content requests pin when necessary.
|
||||
|
||||
---
|
||||
|
|
@ -1,146 +0,0 @@
|
|||
---
|
||||
slug: server-root-path-incident
|
||||
title: "Incident Report: SERVER_ROOT_PATH regression broke UI routing"
|
||||
date: 2026-02-21T10:00:00
|
||||
authors:
|
||||
- yuneng
|
||||
- ishaan-alt
|
||||
- krrish
|
||||
tags: [incident-report, ui, stability]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
**Date:** January 22, 2026
|
||||
**Duration:** ~4 days (until fix merged January 26, 2026)
|
||||
**Severity:** High
|
||||
**Status:** Resolved
|
||||
|
||||
> **Note:** This fix is available starting from LiteLLM `v1.81.3.rc.6` or higher.
|
||||
|
||||
## Summary
|
||||
|
||||
A PR ([`#19467`](https://github.com/BerriAI/litellm/pull/19467)) accidentally removed the `root_path=server_root_path` parameter from the FastAPI app initialization in `proxy_server.py`. This caused the proxy to ignore the `SERVER_ROOT_PATH` environment variable when serving the UI. Users who deploy LiteLLM behind a reverse proxy with a path prefix (e.g., `/api/v1` or `/llmproxy`) found that all UI pages returned 404 Not Found.
|
||||
|
||||
- **LLM API calls:** No impact. API routing was unaffected.
|
||||
- **UI pages:** All UI pages returned 404 for deployments using `SERVER_ROOT_PATH`.
|
||||
- **Swagger/OpenAPI docs:** Broken when accessed through the configured root path.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
---
|
||||
|
||||
## Background
|
||||
|
||||
Many LiteLLM deployments run behind a reverse proxy (e.g., Nginx, Traefik, AWS ALB) that routes traffic to LiteLLM under a path prefix. FastAPI's `root_path` parameter tells the application about this prefix so it can correctly serve static files, generate URLs, and handle routing.
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant User as User Browser
|
||||
participant RP as Reverse Proxy
|
||||
participant LP as LiteLLM Proxy
|
||||
|
||||
User->>RP: GET /llmproxy/ui/
|
||||
RP->>LP: GET /ui/ (X-Forwarded-Prefix: /llmproxy)
|
||||
|
||||
Note over LP: Before regression:<br/>FastAPI root_path="/llmproxy"<br/>→ Serves UI correctly
|
||||
|
||||
Note over LP: After regression:<br/>FastAPI root_path=""<br/>→ UI assets resolve to wrong paths<br/>→ 404 Not Found
|
||||
```
|
||||
|
||||
The `root_path` parameter was present in `proxy_server.py` since early versions of LiteLLM. It was removed as a side effect of PR [#19467](https://github.com/BerriAI/litellm/pull/19467), which was intended to fix a different UI 404 issue.
|
||||
|
||||
---
|
||||
|
||||
## Root cause
|
||||
|
||||
PR [#19467](https://github.com/BerriAI/litellm/pull/19467) (`73d49f8`) removed the `root_path=server_root_path` line from the `FastAPI()` constructor in `proxy_server.py`:
|
||||
|
||||
```diff
|
||||
app = FastAPI(
|
||||
docs_url=_get_docs_url(),
|
||||
redoc_url=_get_redoc_url(),
|
||||
title=_title,
|
||||
description=_description,
|
||||
version=version,
|
||||
- root_path=server_root_path,
|
||||
lifespan=proxy_startup_event,
|
||||
)
|
||||
```
|
||||
|
||||
Without `root_path`, FastAPI treated all requests as if the application was mounted at `/`, causing path mismatches for any deployment using `SERVER_ROOT_PATH`.
|
||||
|
||||
The regression went undetected because:
|
||||
|
||||
1. **No automated test** verified that `root_path` was set on the FastAPI app.
|
||||
2. **No manual test procedure** existed for `SERVER_ROOT_PATH` functionality.
|
||||
3. **Default deployments** (without `SERVER_ROOT_PATH`) were unaffected, so most CI tests passed.
|
||||
|
||||
---
|
||||
|
||||
## Remediation
|
||||
|
||||
| # | Action | Status | Code |
|
||||
| --- | ------------------------------------------------------------------------------------------------- | ------- | -------------------------------------------------------------------------------------------------------------------------- |
|
||||
| 1 | Restore `root_path=server_root_path` in FastAPI app initialization | ✅ Done | [`#19790`](https://github.com/BerriAI/litellm/pull/19790) (`5426b3c`) |
|
||||
| 2 | Add unit tests for `get_server_root_path()` and FastAPI app initialization | ✅ Done | [`test_server_root_path.py`](https://github.com/BerriAI/litellm/blob/main/tests/proxy_unit_tests/test_server_root_path.py) |
|
||||
| 3 | Add CI workflow that builds Docker image and tests UI routing with `SERVER_ROOT_PATH` on every PR | ✅ Done | [`test_server_root_path.yml`](https://github.com/BerriAI/litellm/blob/main/.github/workflows/test_server_root_path.yml) |
|
||||
| 4 | Document manual test procedure for `SERVER_ROOT_PATH` | ✅ Done | [Discussion #8495](https://github.com/BerriAI/litellm/discussions/8495) |
|
||||
|
||||
---
|
||||
|
||||
## CI workflow details
|
||||
|
||||
The new [`test_server_root_path.yml`](https://github.com/BerriAI/litellm/blob/main/.github/workflows/test_server_root_path.yml) workflow runs on every PR against `main`. It:
|
||||
|
||||
1. Builds the LiteLLM Docker image
|
||||
2. Starts a container with `SERVER_ROOT_PATH` set (tests both `/api/v1` and `/llmproxy`)
|
||||
3. Verifies the UI returns valid HTML at `{ROOT_PATH}/ui/`
|
||||
4. Fails the workflow if the UI is unreachable
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
A["PR opened/updated"] --> B["Build Docker image"]
|
||||
B --> C["Start container with SERVER_ROOT_PATH=/api/v1"]
|
||||
B --> D["Start container with SERVER_ROOT_PATH=/llmproxy"]
|
||||
C --> E["curl {ROOT_PATH}/ui/ → expect HTML"]
|
||||
D --> F["curl {ROOT_PATH}/ui/ → expect HTML"]
|
||||
E -->|"HTML found"| G["✅ Pass"]
|
||||
E -->|"404 or no HTML"| H["❌ Fail Workflow"]
|
||||
F -->|"HTML found"| G
|
||||
F -->|"404 or no HTML"| H
|
||||
|
||||
style G fill:#d4edda,stroke:#28a745
|
||||
style H fill:#f8d7da,stroke:#dc3545
|
||||
```
|
||||
|
||||
This prevents future regressions where changes to `proxy_server.py` accidentally break `SERVER_ROOT_PATH` support.
|
||||
|
||||
---
|
||||
|
||||
## Timeline
|
||||
|
||||
| Time (UTC) | Event |
|
||||
| ------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------ |
|
||||
| Jan 22, 2026 04:20 | PR [#19467](https://github.com/BerriAI/litellm/pull/19467) merged, removing `root_path=server_root_path` |
|
||||
| Jan 22–26 | Users on nightly builds report UI 404 errors when using `SERVER_ROOT_PATH` |
|
||||
| Jan 26, 2026 17:48 | Fix PR [#19790](https://github.com/BerriAI/litellm/pull/19790) merged, restoring `root_path=server_root_path` |
|
||||
| Feb 18, 2026 | CI workflow [`test_server_root_path.yml`](https://github.com/BerriAI/litellm/blob/main/.github/workflows/test_server_root_path.yml) added to run on every PR |
|
||||
|
||||
---
|
||||
|
||||
## Resolution steps for users
|
||||
|
||||
For users still experiencing issues, update to the latest LiteLLM version:
|
||||
|
||||
```bash
|
||||
pip install --upgrade litellm
|
||||
```
|
||||
|
||||
Verify your `SERVER_ROOT_PATH` is correctly set:
|
||||
|
||||
```bash
|
||||
# In your environment or docker-compose.yml
|
||||
SERVER_ROOT_PATH="/your-prefix"
|
||||
```
|
||||
|
||||
Then confirm the UI is accessible at `http://your-host:4000/your-prefix/ui/`.
|
||||
|
|
@ -1,85 +0,0 @@
|
|||
---
|
||||
slug: sub-millisecond-proxy-overhead
|
||||
title: "Achieving Sub-Millisecond Proxy Overhead"
|
||||
date: 2026-02-02T10:00:00
|
||||
authors:
|
||||
- alexsander
|
||||
- krrish
|
||||
- ishaan-alt
|
||||
description: "Our Q1 performance target and architectural direction for achieving sub-millisecond proxy overhead on modest hardware."
|
||||
tags: [performance, architecture]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
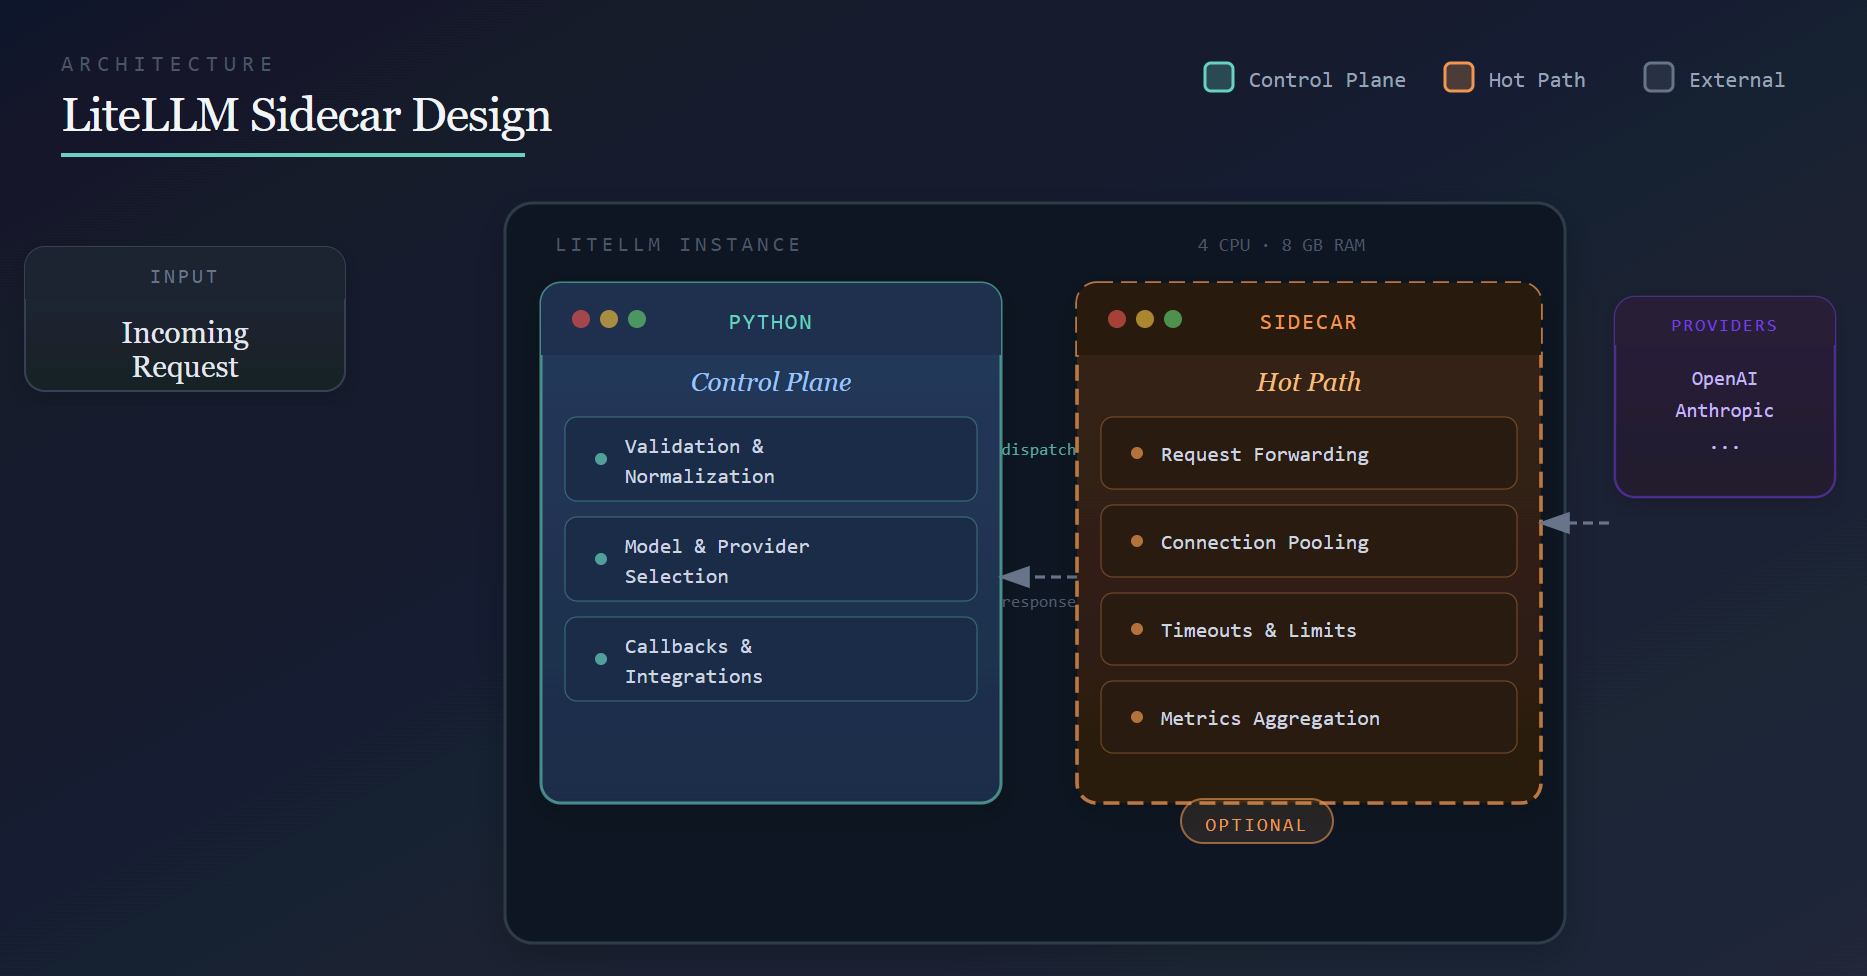
|
||||
|
||||
# Achieving Sub-Millisecond Proxy Overhead
|
||||
|
||||
## Introduction
|
||||
|
||||
Our Q1 performance target is to aggressively move toward sub-millisecond proxy overhead on a single instance with 4 CPUs and 8 GB of RAM, and to continue pushing that boundary over time. Our broader goal is to make LiteLLM inexpensive to deploy, lightweight, and fast. This post outlines the architectural direction behind that effort.
|
||||
|
||||
Proxy overhead refers to the latency introduced by LiteLLM itself, independent of the upstream provider.
|
||||
|
||||
To measure it, we run the same workload directly against the provider and through LiteLLM at identical QPS (for example, 1,000 QPS) and compare the latency delta. To reduce noise, the load generator, LiteLLM, and a mock LLM endpoint all run on the same machine, ensuring the difference reflects proxy overhead rather than network latency.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
---
|
||||
|
||||
## Where We're Coming From
|
||||
|
||||
Under the same benchmark originally conducted by [TensorZero](https://www.tensorzero.com/docs/gateway/benchmarks), LiteLLM previously failed at around 1,000 QPS.
|
||||
|
||||
That is no longer the case. Today, LiteLLM can be stress-tested at 1,000 QPS with no failures and can scale up to 5,000 QPS without failures on a 4-CPU, 8-GB RAM single instance setup.
|
||||
|
||||
This establishes a more up to date baseline and provides useful context as we continue working on proxy overhead and overall performance.
|
||||
|
||||
---
|
||||
|
||||
## Design Choice
|
||||
|
||||
Achieving sub-millisecond proxy overhead with a Python-based system requires being deliberate about where work happens.
|
||||
|
||||
Python is a strong fit for flexibility and extensibility: provider abstraction, configuration-driven routing, and a rich callback ecosystem. These are areas where development velocity and correctness matter more than raw throughput.
|
||||
|
||||
At higher request rates, however, certain classes of work become expensive when executed inside the Python process on every request. Rather than rewriting LiteLLM or introducing complex deployment requirements, we adopt an optional **sidecar architecture**.
|
||||
|
||||
This architectural change is how we intend to make LiteLLM **permanently fast**. While it supports our near-term performance targets, it is a long-term investment.
|
||||
|
||||
Python continues to own:
|
||||
|
||||
- Request validation and normalization
|
||||
- Model and provider selection
|
||||
- Callbacks and integrations
|
||||
|
||||
The sidecar owns **performance-critical execution**, such as:
|
||||
|
||||
- Efficient request forwarding
|
||||
- Connection reuse and pooling
|
||||
- Enforcing timeouts and limits
|
||||
- Aggregating high-frequency metrics
|
||||
|
||||
This separation allows each component to focus on what it does best: Python acts as the control plane, while the sidecar handles the hot path.
|
||||
|
||||
---
|
||||
|
||||
### Why the Sidecar Is Optional
|
||||
|
||||
The sidecar is intentionally **optional**.
|
||||
|
||||
This allows us to ship it incrementally, validate it under real-world workloads, and avoid making it a hard dependency before it is fully battle-tested across all LiteLLM features.
|
||||
|
||||
Just as importantly, this ensures that self-hosting LiteLLM remains simple. The sidecar is bundled and started automatically, requires no additional infrastructure, and can be disabled entirely. From a user's perspective, LiteLLM continues to behave like a single service.
|
||||
|
||||
As of today, the sidecar is an optimization, not a requirement.
|
||||
|
||||
---
|
||||
|
||||
## Conclusion
|
||||
|
||||
Sub-millisecond proxy overhead is not achieved through a single optimization, but through architectural changes.
|
||||
|
||||
By keeping Python focused on orchestration and extensibility, and offloading performance-critical execution to a sidecar, we establish a foundation for making LiteLLM **permanently fast over time**—even on modest hardware such as a 1-CPU, 2-GB RAM instance, while keeping deployment and self-hosting simple.
|
||||
|
||||
This work extends beyond Q1, and we will continue sharing benchmarks and updates as the architecture evolves.
|
||||
|
|
@ -1,121 +0,0 @@
|
|||
---
|
||||
slug: video_characters_api
|
||||
title: "New Video Characters, Edit and Extension API support"
|
||||
date: 2026-03-16T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
- krrish
|
||||
- ishaan-alt
|
||||
description: "LiteLLM now supports creating, retrieving, and managing reusable video characters across multiple video generations."
|
||||
tags: [videos, characters, proxy, routing]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
LiteLLM now supoports videos character, edit and extension apis.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
## What's New
|
||||
|
||||
Four new endpoints for video character operations:
|
||||
- **Create character** - Upload a video to create a reusable asset
|
||||
- **Get character** - Retrieve character metadata
|
||||
- **Edit video** - Modify generated videos
|
||||
- **Extend video** - Continue clips with character consistency
|
||||
|
||||
**Available from:** LiteLLM v1.83.0+
|
||||
|
||||
## Quick Example
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
# Create character from video
|
||||
character = litellm.avideo_create_character(
|
||||
name="Luna",
|
||||
video=open("luna.mp4", "rb"),
|
||||
custom_llm_provider="openai",
|
||||
model="sora-2"
|
||||
)
|
||||
print(f"Character: {character.id}")
|
||||
|
||||
# Use in generation
|
||||
video = litellm.avideo(
|
||||
model="sora-2",
|
||||
prompt="Luna dances through a magical forest.",
|
||||
characters=[{"id": character.id}],
|
||||
seconds="8"
|
||||
)
|
||||
|
||||
# Get character info
|
||||
fetched = litellm.avideo_get_character(
|
||||
character_id=character.id,
|
||||
custom_llm_provider="openai"
|
||||
)
|
||||
|
||||
# Edit with character preserved
|
||||
edited = litellm.avideo_edit(
|
||||
video_id=video.id,
|
||||
prompt="Add warm golden lighting"
|
||||
)
|
||||
|
||||
# Extend sequence
|
||||
extended = litellm.avideo_extension(
|
||||
video_id=video.id,
|
||||
prompt="Luna waves goodbye",
|
||||
seconds="5"
|
||||
)
|
||||
```
|
||||
|
||||
## Via Proxy
|
||||
|
||||
```bash
|
||||
# Create character
|
||||
curl -X POST "http://localhost:4000/v1/videos/characters" \
|
||||
-H "Authorization: Bearer sk-litellm-key" \
|
||||
-F "video=@luna.mp4" \
|
||||
-F "name=Luna"
|
||||
|
||||
# Get character
|
||||
curl -X GET "http://localhost:4000/v1/videos/characters/char_abc123def456" \
|
||||
-H "Authorization: Bearer sk-litellm-key"
|
||||
|
||||
# Edit video
|
||||
curl -X POST "http://localhost:4000/v1/videos/edits" \
|
||||
-H "Authorization: Bearer sk-litellm-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"video": {"id": "video_xyz789"},
|
||||
"prompt": "Add warm golden lighting and enhance colors"
|
||||
}'
|
||||
|
||||
# Extend video
|
||||
curl -X POST "http://localhost:4000/v1/videos/extensions" \
|
||||
-H "Authorization: Bearer sk-litellm-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"video": {"id": "video_xyz789"},
|
||||
"prompt": "Luna waves goodbye and walks into the sunset",
|
||||
"seconds": "5"
|
||||
}'
|
||||
```
|
||||
|
||||
## Managed Character IDs
|
||||
|
||||
LiteLLM automatically encodes provider and model metadata into character IDs:
|
||||
|
||||
**What happens:**
|
||||
```
|
||||
Upload character "Luna" with model "sora-2" on OpenAI
|
||||
↓
|
||||
LiteLLM creates: char_abc123def456 (contains provider + model_id)
|
||||
↓
|
||||
When you reference it later, LiteLLM decodes automatically
|
||||
↓
|
||||
Router knows exactly which deployment to use
|
||||
```
|
||||
|
||||
**Behind the scenes:**
|
||||
- Character ID format: `character_<base64_encoded_metadata>`
|
||||
- Metadata includes: provider, model_id, original_character_id
|
||||
- Transparent to you - just use the ID, LiteLLM handles routing
|
||||
|
|
@ -1,108 +0,0 @@
|
|||
---
|
||||
slug: vllm-embeddings-incident
|
||||
title: "Incident Report: vLLM Embeddings Broken by encoding_format Parameter"
|
||||
date: 2026-02-18T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
- krrish
|
||||
- ishaan-alt
|
||||
tags: [incident-report, embeddings, vllm]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
**Date:** Feb 16, 2026
|
||||
**Duration:** ~3 hours
|
||||
**Severity:** High (for vLLM embedding users)
|
||||
**Status:** Resolved
|
||||
|
||||
## Summary
|
||||
|
||||
A commit ([`dbcae4a`](https://github.com/BerriAI/litellm/commit/dbcae4aca5836770d0e9cd43abab0333c3d61ab2)) intended to fix OpenAI SDK behavior broke vLLM embeddings by explicitly passing `encoding_format=None` in API requests. vLLM rejects this with error: `"unknown variant \`\`, expected float or base64"`.
|
||||
|
||||
- **vLLM embedding calls:** Complete failure - all requests rejected
|
||||
- **Other providers:** No impact - OpenAI and other providers functioned normally
|
||||
- **Other vLLM functionality:** No impact - only embeddings were affected
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
---
|
||||
|
||||
## Background
|
||||
|
||||
The `encoding_format` parameter for embeddings specifies whether vectors should be returned as `float` arrays or `base64` encoded strings. Different providers have different expectations:
|
||||
|
||||
- **OpenAI SDK:** If `encoding_format` is omitted, the SDK adds a default value of `"float"`
|
||||
- **vLLM:** Strictly validates `encoding_format` - only accepts `"float"`, `"base64"`, or complete omission. Rejects `None` or empty string values.
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
A["1. User calls litellm.embedding()
|
||||
litellm/main.py"] --> B["2. Transform request for provider
|
||||
litellm/llms/openai_like/embedding/handler.py"]
|
||||
B --> C["3. Send request to vLLM endpoint"]
|
||||
C -->|"encoding_format omitted"| D["4a. ✅ vLLM processes request"]
|
||||
C -->|"encoding_format='float' or 'base64'"| D
|
||||
C -->|"encoding_format=None or ''"| E["4b. ❌ vLLM rejects with error:
|
||||
'unknown variant, expected float or base64'"]
|
||||
|
||||
style D fill:#d4edda,stroke:#28a745
|
||||
style E fill:#f8d7da,stroke:#dc3545
|
||||
style B fill:#fff3cd,stroke:#ffc107
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Root cause
|
||||
|
||||
A well-intentioned fix for OpenAI SDK behavior inadvertently broke vLLM embeddings:
|
||||
|
||||
**The Breaking Change ([`dbcae4a`](https://github.com/BerriAI/litellm/commit/dbcae4aca5836770d0e9cd43abab0333c3d61ab2)):**
|
||||
|
||||
In `litellm/main.py`, the code was changed to explicitly set `encoding_format=None` instead of omitting it:
|
||||
|
||||
```python
|
||||
# Added in dbcae4a
|
||||
if encoding_format is not None:
|
||||
optional_params["encoding_format"] = encoding_format
|
||||
else:
|
||||
# Omitting causes openai sdk to add default value of "float"
|
||||
optional_params["encoding_format"] = None
|
||||
```
|
||||
|
||||
This fix worked correctly for OpenAI - explicitly passing `None` prevented the SDK from adding its default value. However, vLLM's strict parameter validation rejected `None` values, causing all embedding requests to fail.
|
||||
|
||||
---
|
||||
|
||||
## The Fix
|
||||
|
||||
Fix deployed ([`55348dd`](https://github.com/BerriAI/litellm/commit/55348dd9c51b5b028f676d25ad023b8f052fc071)). The solution filters out `None` and empty string values from `optional_params` before sending requests to OpenAI-like providers (including vLLM).
|
||||
|
||||
**In `litellm/llms/openai_like/embedding/handler.py`:**
|
||||
|
||||
```python
|
||||
# Before (broken)
|
||||
data = {"model": model, "input": input, **optional_params}
|
||||
|
||||
# After (fixed)
|
||||
filtered_optional_params = {k: v for k, v in optional_params.items() if v not in (None, '')}
|
||||
data = {"model": model, "input": input, **filtered_optional_params}
|
||||
```
|
||||
|
||||
This ensures:
|
||||
- Valid values (`"float"`, `"base64"`) are preserved and sent
|
||||
- `None` and empty string values are filtered out (parameter omitted entirely)
|
||||
- OpenAI SDK no longer adds defaults because liteLLM handles the parameter upstream
|
||||
|
||||
---
|
||||
|
||||
## Remediation
|
||||
|
||||
| # | Action | Status | Code |
|
||||
|---|---|---|---|
|
||||
| 1 | Filter `None` and empty string values in OpenAI-like embedding handler | ✅ Done | [`handler.py#L108`](https://github.com/BerriAI/litellm/blob/main/litellm/llms/openai_like/embedding/handler.py#L108) |
|
||||
| 2 | Unit tests for parameter filtering (None, empty string, valid values) | ✅ Done | [`test_openai_like_embedding.py`](https://github.com/BerriAI/litellm/blob/main/tests/test_litellm/llms/openai_like/embedding/test_openai_like_embedding.py) |
|
||||
| 3 | Transformation tests for hosted_vllm embedding config | ✅ Done | [`test_hosted_vllm_embedding_transformation.py`](https://github.com/BerriAI/litellm/blob/main/tests/test_litellm/llms/hosted_vllm/embedding/test_hosted_vllm_embedding_transformation.py) |
|
||||
| 4 | E2E tests with actual vLLM endpoint | ✅ Done | [`test_hosted_vllm_embedding_e2e.py`](https://github.com/BerriAI/litellm/blob/main/tests/test_litellm/llms/hosted_vllm/embedding/test_hosted_vllm_embedding_e2e.py) |
|
||||
| 5 | Validate JSON payload structure matches vLLM expectations | ✅ Done | Tests verify exact JSON sent to endpoint |
|
||||
|
||||
---
|
||||
|
|
@ -1,265 +0,0 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Agent Gateway (A2A Protocol) - Overview
|
||||
|
||||
Add A2A Agents on LiteLLM AI Gateway, Invoke agents in A2A Protocol, track request/response logs in LiteLLM Logs. Manage which Teams, Keys can access which Agents onboarded.
|
||||
|
||||
<Image
|
||||
img={require('../img/a2a_gateway.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0', borderRadius: '8px'}}
|
||||
/>
|
||||
|
||||
<br />
|
||||
<br />
|
||||
|
||||
| Feature | Supported |
|
||||
|---------|-----------|
|
||||
| Supported Agent Providers | A2A, Vertex AI Agent Engine, LangGraph, Azure AI Foundry, Bedrock AgentCore, Pydantic AI |
|
||||
| Logging | ✅ |
|
||||
| Load Balancing | ✅ |
|
||||
| Streaming | ✅ |
|
||||
| [Iteration Budgets](a2a_iteration_budgets) | ✅ |
|
||||
|
||||
|
||||
:::tip
|
||||
|
||||
LiteLLM follows the [A2A (Agent-to-Agent) Protocol](https://github.com/google/A2A) for invoking agents.
|
||||
|
||||
:::
|
||||
|
||||
## Adding your Agent
|
||||
|
||||
### Add A2A Agents
|
||||
|
||||
You can add A2A-compatible agents through the LiteLLM Admin UI.
|
||||
|
||||
1. Navigate to the **Agents** tab
|
||||
2. Click **Add Agent**
|
||||
3. Enter the agent name (e.g., `ij-local`) and the URL of your A2A agent
|
||||
|
||||
<Image
|
||||
img={require('../img/add_agent_1.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0'}}
|
||||
/>
|
||||
|
||||
The URL should be the invocation URL for your A2A agent (e.g., `http://localhost:10001`).
|
||||
|
||||
|
||||
### Add Azure AI Foundry Agents
|
||||
|
||||
Follow [this guide, to add your azure ai foundry agent to LiteLLM Agent Gateway](./providers/azure_ai_agents#litellm-a2a-gateway)
|
||||
|
||||
### Add Vertex AI Agent Engine
|
||||
|
||||
Follow [this guide, to add your Vertex AI Agent Engine to LiteLLM Agent Gateway](./providers/vertex_ai_agent_engine)
|
||||
|
||||
### Add Bedrock AgentCore Agents
|
||||
|
||||
Follow [this guide, to add your bedrock agentcore agent to LiteLLM Agent Gateway](./providers/bedrock_agentcore#litellm-a2a-gateway)
|
||||
|
||||
### Add LangGraph Agents
|
||||
|
||||
Follow [this guide, to add your langgraph agent to LiteLLM Agent Gateway](./providers/langgraph#litellm-a2a-gateway)
|
||||
|
||||
### Add Pydantic AI Agents
|
||||
|
||||
Follow [this guide, to add your pydantic ai agent to LiteLLM Agent Gateway](./providers/pydantic_ai_agent#litellm-a2a-gateway)
|
||||
|
||||
## Invoking your Agents
|
||||
|
||||
See the [Invoking A2A Agents](./a2a_invoking_agents) guide to learn how to call your agents using:
|
||||
- **A2A SDK** - Native A2A protocol with full support for tasks and artifacts
|
||||
- **OpenAI SDK** - Familiar `/chat/completions` interface with `a2a/` model prefix
|
||||
|
||||
## Tracking Agent Logs
|
||||
|
||||
After invoking an agent, you can view the request logs in the LiteLLM **Logs** tab.
|
||||
|
||||
The logs show:
|
||||
- **Request/Response content** sent to and received from the agent
|
||||
- **User, Key, Team** information for tracking who made the request
|
||||
- **Latency and cost** metrics
|
||||
|
||||
<Image
|
||||
img={require('../img/agent2.png')}
|
||||
style={{width: '100%', display: 'block', margin: '2rem auto'}}
|
||||
/>
|
||||
|
||||
|
||||
## Forwarding LiteLLM Context Headers
|
||||
|
||||
When LiteLLM invokes your A2A agent, it sends special headers that enable:
|
||||
- **Trace Grouping**: All LLM calls from the same agent execution appear under one trace
|
||||
- **Agent Spend Tracking**: Costs are attributed to the specific agent
|
||||
|
||||
| Header | Purpose |
|
||||
|--------|---------|
|
||||
| `X-LiteLLM-Trace-Id` | Links all LLM calls to the same execution flow |
|
||||
| `X-LiteLLM-Agent-Id` | Attributes spend to the correct agent |
|
||||
|
||||
|
||||
To enable these features, your A2A server must **forward these headers** to any LLM calls it makes back to LiteLLM.
|
||||
|
||||
### Implementation Steps
|
||||
|
||||
**Step 1: Extract headers from incoming A2A request**
|
||||
```python def get_litellm_headers(request) -> dict:
|
||||
"""Extract X-LiteLLM-* headers from incoming A2A request."""
|
||||
all_headers = request.call_context.state.get('headers', {})
|
||||
return {
|
||||
k: v for k, v in all_headers.items()
|
||||
if k.lower().startswith('x-litellm-')
|
||||
}
|
||||
```
|
||||
|
||||
**Step 2: Forward headers to your LLM calls**
|
||||
Pass the extracted headers when making calls back to LiteLLM:
|
||||
<Tabs>
|
||||
<TabItem value="openai" label="OpenAI SDK" default>
|
||||
|
||||
```python from openai import OpenAI
|
||||
|
||||
headers = get_litellm_headers(request)
|
||||
|
||||
client = OpenAI(
|
||||
api_key="sk-your-litellm-key",
|
||||
base_url="http://localhost:4000",
|
||||
default_headers=headers, # Forward headers
|
||||
)
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="gpt-4o",
|
||||
messages=[{"role": "user", "content": "Hello"}]
|
||||
)
|
||||
```
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="langchain" label="LangChain">
|
||||
|
||||
```python
|
||||
from langchain_openai import ChatOpenAI
|
||||
|
||||
headers = get_litellm_headers(request)
|
||||
|
||||
llm = ChatOpenAI(
|
||||
model="gpt-4o",
|
||||
openai_api_key="sk-your-litellm-key",
|
||||
base_url="http://localhost:4000",
|
||||
default_headers=headers, # Forward headers
|
||||
)
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="litellm" label="LiteLLM SDK">
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
headers = get_litellm_headers(request)
|
||||
|
||||
response = litellm.completion(
|
||||
model="gpt-4o",
|
||||
messages=[{"role": "user", "content": "Hello"}],
|
||||
api_base="http://localhost:4000",
|
||||
extra_headers=headers, # Forward headers
|
||||
)
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="requests" label="HTTP (requests/httpx)">
|
||||
|
||||
```python
|
||||
import httpx
|
||||
|
||||
headers = get_litellm_headers(request)
|
||||
headers["Authorization"] = "Bearer sk-your-litellm-key"
|
||||
|
||||
response = httpx.post(
|
||||
"http://localhost:4000/v1/chat/completions",
|
||||
headers=headers,
|
||||
json={"model": "gpt-4o", "messages": [{"role": "user", "content": "Hello"}]}
|
||||
)
|
||||
```
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Result
|
||||
|
||||
With header forwarding enabled, you'll see:
|
||||
|
||||
**Trace Grouping in Langfuse:**
|
||||
|
||||
<Image
|
||||
img={require('../img/a2a_trace_grouping.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0', borderRadius: '8px'}}
|
||||
/>
|
||||
|
||||
**Agent Spend Attribution:**
|
||||
|
||||
<Image
|
||||
img={require('../img/a2a_agent_spend.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0', borderRadius: '8px'}}
|
||||
/>
|
||||
|
||||
## API Reference
|
||||
|
||||
### Endpoint
|
||||
|
||||
```
|
||||
POST /a2a/{agent_name}/message/send
|
||||
```
|
||||
|
||||
### Authentication
|
||||
|
||||
Include your LiteLLM Virtual Key in the `Authorization` header:
|
||||
|
||||
```
|
||||
Authorization: Bearer sk-your-litellm-key
|
||||
```
|
||||
|
||||
### Request Format
|
||||
|
||||
LiteLLM follows the [A2A JSON-RPC 2.0 specification](https://github.com/google/A2A):
|
||||
|
||||
```json title="Request Body"
|
||||
{
|
||||
"jsonrpc": "2.0",
|
||||
"id": "unique-request-id",
|
||||
"method": "message/send",
|
||||
"params": {
|
||||
"message": {
|
||||
"role": "user",
|
||||
"parts": [{"kind": "text", "text": "Your message here"}],
|
||||
"messageId": "unique-message-id"
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Response Format
|
||||
|
||||
```json title="Response"
|
||||
{
|
||||
"jsonrpc": "2.0",
|
||||
"id": "unique-request-id",
|
||||
"result": {
|
||||
"kind": "task",
|
||||
"id": "task-id",
|
||||
"contextId": "context-id",
|
||||
"status": {"state": "completed", "timestamp": "2025-01-01T00:00:00Z"},
|
||||
"artifacts": [
|
||||
{
|
||||
"artifactId": "artifact-id",
|
||||
"name": "response",
|
||||
"parts": [{"kind": "text", "text": "Agent response here"}]
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Agent Registry
|
||||
|
||||
Want to create a central registry so your team can discover what agents are available within your company?
|
||||
|
||||
Use the [AI Hub](./proxy/ai_hub) to make agents public and discoverable across your organization. This allows developers to browse available agents without needing to rebuild them.
|
||||
|
|
@ -1,252 +0,0 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# A2A Agent Authentication Headers
|
||||
|
||||
Forward authentication credentials (Bearer tokens, API keys, etc.) from clients to backend A2A agents.
|
||||
|
||||
## Overview
|
||||
|
||||
When LiteLLM proxies a request to a backend A2A agent, the agent may require its own authentication headers. There are three ways to supply them:
|
||||
|
||||
| Method | Who configures | How it works |
|
||||
|---|---|---|
|
||||
| **Static headers** | Admin (UI / API) | Always sent, regardless of client request |
|
||||
| **Forward client headers** | Admin (UI / API) | Header names to extract from client request and forward |
|
||||
| **Convention-based** | Client (no admin config) | Client sends `x-a2a-{agent_name}-{header}` — automatically routed |
|
||||
|
||||
All three methods can be combined. **Static headers always win** on key conflicts.
|
||||
|
||||
---
|
||||
|
||||
## Method 1 — Static Headers
|
||||
|
||||
Admin-configured headers that are always sent to the backend agent. Use this for server-to-server tokens or internal credentials that clients should never see or override.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI">
|
||||
|
||||
1. Go to **Agents** in the LiteLLM dashboard.
|
||||
2. Create or edit an agent.
|
||||
3. Open the **Authentication Headers** panel.
|
||||
4. Under **Static Headers**, click **Add Static Header** and fill in the header name and value.
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="REST API">
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/v1/agents \
|
||||
-H "Authorization: Bearer sk-admin" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"agent_name": "my-agent",
|
||||
"agent_card_params": { ... },
|
||||
"static_headers": {
|
||||
"Authorization": "Bearer internal-server-token",
|
||||
"X-Internal-Service": "litellm-proxy"
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
To update an existing agent:
|
||||
|
||||
```bash
|
||||
curl -X PATCH http://localhost:4000/v1/agents/{agent_id} \
|
||||
-H "Authorization: Bearer sk-admin" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"static_headers": {
|
||||
"Authorization": "Bearer new-token"
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
**Client call — no special headers needed:**
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/a2a/my-agent \
|
||||
-H "Authorization: Bearer sk-client-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"jsonrpc": "2.0", "id": "1", "method": "message/send",
|
||||
"params": { "message": { "role": "user", "parts": [{"kind": "text", "text": "Hello"}], "messageId": "msg-1" } }
|
||||
}'
|
||||
```
|
||||
|
||||
The backend agent receives `Authorization: Bearer internal-server-token` without the client ever knowing the value.
|
||||
|
||||
---
|
||||
|
||||
## Method 2 — Forward Client Headers
|
||||
|
||||
Admin specifies a list of header **names**. When the client sends a request that includes those headers, LiteLLM extracts their values and forwards them to the backend agent. The client controls the values; the admin controls which headers are eligible to be forwarded.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI">
|
||||
|
||||
1. Go to **Agents** in the LiteLLM dashboard.
|
||||
2. Create or edit an agent.
|
||||
3. Open the **Authentication Headers** panel.
|
||||
4. Under **Forward Client Headers**, type header names and press **Enter** (e.g. `x-api-key`, `Authorization`).
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="REST API">
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/v1/agents \
|
||||
-H "Authorization: Bearer sk-admin" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"agent_name": "my-agent",
|
||||
"agent_card_params": { ... },
|
||||
"extra_headers": ["x-api-key", "x-user-token"]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
**Client call — include the forwarded headers:**
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/a2a/my-agent \
|
||||
-H "Authorization: Bearer sk-client-key" \
|
||||
-H "x-api-key: user-secret-value" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{ ... }'
|
||||
```
|
||||
|
||||
The backend agent receives `x-api-key: user-secret-value`.
|
||||
|
||||
:::note
|
||||
Header name matching is **case-insensitive**. If the client sends `X-API-Key` and `extra_headers` lists `x-api-key`, they match.
|
||||
:::
|
||||
|
||||
---
|
||||
|
||||
## Method 3 — Convention-Based Forwarding
|
||||
|
||||
Clients can forward headers to a specific agent without any admin pre-configuration by using the naming convention:
|
||||
|
||||
```
|
||||
x-a2a-{agent_name_or_id}-{header_name}: value
|
||||
```
|
||||
|
||||
LiteLLM parses these headers automatically and routes them to the matching agent only.
|
||||
|
||||
**Examples:**
|
||||
|
||||
| Client header sent | Agent name/ID | Forwarded as |
|
||||
|---|---|---|
|
||||
| `x-a2a-my-agent-authorization: Bearer tok` | `my-agent` | `authorization: Bearer tok` |
|
||||
| `x-a2a-my-agent-x-api-key: secret` | `my-agent` | `x-api-key: secret` |
|
||||
| `x-a2a-abc123-authorization: Bearer tok` | agent ID `abc123` | `authorization: Bearer tok` |
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/a2a/my-agent \
|
||||
-H "Authorization: Bearer sk-client-key" \
|
||||
-H "x-a2a-my-agent-authorization: Bearer agent-specific-token" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{ ... }'
|
||||
```
|
||||
|
||||
The `x-a2a-other-agent-authorization` header sent in the same request is **not** forwarded to `my-agent` — it is silently ignored.
|
||||
|
||||
:::tip Matches both agent name and agent ID
|
||||
Both the human-readable name (e.g. `my-agent`) and the UUID (e.g. `abc123-...`) are valid. Use whichever is convenient for the client.
|
||||
:::
|
||||
|
||||
---
|
||||
|
||||
## Merge Precedence
|
||||
|
||||
When multiple methods supply the same header name, **static headers win**:
|
||||
|
||||
```
|
||||
dynamic (forwarded/convention) → merged ← static (overlays, wins)
|
||||
```
|
||||
|
||||
Example:
|
||||
|
||||
| Source | `Authorization` value |
|
||||
|---|---|
|
||||
| Client sends (via `extra_headers` or convention) | `Bearer client-token` |
|
||||
| Admin-configured `static_headers` | `Bearer server-token` |
|
||||
| **What the backend agent receives** | **`Bearer server-token`** |
|
||||
|
||||
This ensures admin-controlled credentials cannot be overridden by client requests.
|
||||
|
||||
---
|
||||
|
||||
## Combining All Three Methods
|
||||
|
||||
```bash
|
||||
# Register agent with static + forwarded headers
|
||||
curl -X POST http://localhost:4000/v1/agents \
|
||||
-H "Authorization: Bearer sk-admin" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"agent_name": "my-agent",
|
||||
"agent_card_params": { ... },
|
||||
"static_headers": {
|
||||
"X-Internal-Token": "secret123"
|
||||
},
|
||||
"extra_headers": ["x-user-id"]
|
||||
}'
|
||||
|
||||
# Client call using all three mechanisms
|
||||
curl -X POST http://localhost:4000/a2a/my-agent \
|
||||
-H "Authorization: Bearer sk-client-key" \
|
||||
-H "x-user-id: user-42" \
|
||||
-H "x-a2a-my-agent-x-request-id: req-abc" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{ ... }'
|
||||
```
|
||||
|
||||
The backend agent receives:
|
||||
|
||||
```
|
||||
X-Internal-Token: secret123 ← static header (always)
|
||||
x-user-id: user-42 ← forwarded (in extra_headers)
|
||||
x-request-id: req-abc ← convention-based (x-a2a-my-agent-*)
|
||||
X-LiteLLM-Trace-Id: <uuid> ← LiteLLM internal
|
||||
X-LiteLLM-Agent-Id: <agent-id> ← LiteLLM internal
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Header Isolation
|
||||
|
||||
Each agent invocation uses an isolated HTTP connection. Headers configured for agent A are **never** sent to agent B, even if both agents are running and receiving requests simultaneously.
|
||||
|
||||
---
|
||||
|
||||
## API Reference
|
||||
|
||||
### `POST /v1/agents` / `PATCH /v1/agents/{agent_id}`
|
||||
|
||||
| Field | Type | Description |
|
||||
|---|---|---|
|
||||
| `static_headers` | `object` | `{"Header-Name": "value"}` — always forwarded |
|
||||
| `extra_headers` | `string[]` | Header names to extract from client request and forward |
|
||||
|
||||
### Agent Response
|
||||
|
||||
Both fields are returned in `GET /v1/agents` and `GET /v1/agents/{agent_id}`:
|
||||
|
||||
```json
|
||||
{
|
||||
"agent_id": "...",
|
||||
"agent_name": "my-agent",
|
||||
"static_headers": { "X-Internal-Token": "secret123" },
|
||||
"extra_headers": ["x-user-id"],
|
||||
...
|
||||
}
|
||||
```
|
||||
|
||||
:::caution
|
||||
`static_headers` values are stored in the database and returned by the API. Treat them as you would any credential — do not store sensitive long-lived tokens here if your API is publicly accessible. Consider using short-lived tokens or environment-injected secrets instead.
|
||||
:::
|
||||
|
|
@ -1,259 +0,0 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Agent Permission Management
|
||||
|
||||
Control which A2A agents can be accessed by specific keys or teams in LiteLLM.
|
||||
|
||||
## Overview
|
||||
|
||||
Agent Permission Management lets you restrict which agents a LiteLLM Virtual Key or Team can access. This is useful for:
|
||||
|
||||
- **Multi-tenant environments**: Give different teams access to different agents
|
||||
- **Security**: Prevent keys from invoking agents they shouldn't have access to
|
||||
- **Compliance**: Enforce access policies for sensitive agent workflows
|
||||
|
||||
When permissions are configured:
|
||||
- `GET /v1/agents` only returns agents the key/team can access
|
||||
- `POST /a2a/{agent_id}` (Invoking an agent) returns `403 Forbidden` if access is denied
|
||||
|
||||
## Setting Permissions on a Key
|
||||
|
||||
This example shows how to create a key with agent permissions and test access.
|
||||
|
||||
### 1. Get Your Agent ID
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI">
|
||||
|
||||
1. Go to **Agents** in the sidebar
|
||||
2. Click into the agent you want
|
||||
3. Copy the **Agent ID**
|
||||
|
||||
<Image
|
||||
img={require('../img/agent_id.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0', borderRadius: '8px'}}
|
||||
/>
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
```bash title="List all agents" showLineNumbers
|
||||
curl "http://localhost:4000/v1/agents" \
|
||||
-H "Authorization: Bearer sk-master-key"
|
||||
```
|
||||
|
||||
Response:
|
||||
```json title="Response" showLineNumbers
|
||||
{
|
||||
"agents": [
|
||||
{"agent_id": "agent-123", "name": "Support Agent"},
|
||||
{"agent_id": "agent-456", "name": "Sales Agent"}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### 2. Create a Key with Agent Permissions
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI">
|
||||
|
||||
1. Go to **Keys** → **Create Key**
|
||||
2. Expand **Agent Settings**
|
||||
3. Select the agents you want to allow
|
||||
|
||||
<Image
|
||||
img={require('../img/agent_key.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0', borderRadius: '8px'}}
|
||||
/>
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
```bash title="Create key with agent permissions" showLineNumbers
|
||||
curl -X POST "http://localhost:4000/key/generate" \
|
||||
-H "Authorization: Bearer sk-master-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"object_permission": {
|
||||
"agents": ["agent-123"]
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### 3. Test Access
|
||||
|
||||
**Allowed agent (succeeds):**
|
||||
```bash title="Invoke allowed agent" showLineNumbers
|
||||
curl -X POST "http://localhost:4000/a2a/agent-123" \
|
||||
-H "Authorization: Bearer sk-your-new-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"message": {"role": "user", "parts": [{"type": "text", "text": "Hello"}]}}'
|
||||
```
|
||||
|
||||
**Blocked agent (fails with 403):**
|
||||
```bash title="Invoke blocked agent" showLineNumbers
|
||||
curl -X POST "http://localhost:4000/a2a/agent-456" \
|
||||
-H "Authorization: Bearer sk-your-new-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"message": {"role": "user", "parts": [{"type": "text", "text": "Hello"}]}}'
|
||||
```
|
||||
|
||||
Response:
|
||||
```json title="403 Forbidden Response" showLineNumbers
|
||||
{
|
||||
"error": {
|
||||
"message": "Access denied to agent: agent-456",
|
||||
"code": 403
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Setting Permissions on a Team
|
||||
|
||||
Restrict all keys belonging to a team to only access specific agents.
|
||||
|
||||
### 1. Create a Team with Agent Permissions
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI">
|
||||
|
||||
1. Go to **Teams** → **Create Team**
|
||||
2. Expand **Agent Settings**
|
||||
3. Select the agents you want to allow for this team
|
||||
|
||||
<Image
|
||||
img={require('../img/agent_key.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0', borderRadius: '8px'}}
|
||||
/>
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
```bash title="Create team with agent permissions" showLineNumbers
|
||||
curl -X POST "http://localhost:4000/team/new" \
|
||||
-H "Authorization: Bearer sk-master-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"team_alias": "support-team",
|
||||
"object_permission": {
|
||||
"agents": ["agent-123"]
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
Response:
|
||||
```json title="Response" showLineNumbers
|
||||
{
|
||||
"team_id": "team-abc-123",
|
||||
"team_alias": "support-team"
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### 2. Create a Key for the Team
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI">
|
||||
|
||||
1. Go to **Keys** → **Create Key**
|
||||
2. Select the **Team** from the dropdown
|
||||
|
||||
<Image
|
||||
img={require('../img/agent_team.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0', borderRadius: '8px'}}
|
||||
/>
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
```bash title="Create key for team" showLineNumbers
|
||||
curl -X POST "http://localhost:4000/key/generate" \
|
||||
-H "Authorization: Bearer sk-master-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"team_id": "team-abc-123"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### 3. Test Access
|
||||
|
||||
The key inherits agent permissions from the team.
|
||||
|
||||
**Allowed agent (succeeds):**
|
||||
```bash title="Invoke allowed agent" showLineNumbers
|
||||
curl -X POST "http://localhost:4000/a2a/agent-123" \
|
||||
-H "Authorization: Bearer sk-team-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"message": {"role": "user", "parts": [{"type": "text", "text": "Hello"}]}}'
|
||||
```
|
||||
|
||||
**Blocked agent (fails with 403):**
|
||||
```bash title="Invoke blocked agent" showLineNumbers
|
||||
curl -X POST "http://localhost:4000/a2a/agent-456" \
|
||||
-H "Authorization: Bearer sk-team-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"message": {"role": "user", "parts": [{"type": "text", "text": "Hello"}]}}'
|
||||
```
|
||||
|
||||
## How It Works
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
A[Request to invoke agent] --> B{LiteLLM Virtual Key has agent restrictions?}
|
||||
B -->|Yes| C{LiteLLM Team has agent restrictions?}
|
||||
B -->|No| D{LiteLLM Team has agent restrictions?}
|
||||
|
||||
C -->|Yes| E[Use intersection of key + team permissions]
|
||||
C -->|No| F[Use key permissions only]
|
||||
|
||||
D -->|Yes| G[Inherit team permissions]
|
||||
D -->|No| H[Allow ALL agents]
|
||||
|
||||
E --> I{Agent in allowed list?}
|
||||
F --> I
|
||||
G --> I
|
||||
H --> J[Allow request]
|
||||
|
||||
I -->|Yes| J
|
||||
I -->|No| K[Return 403 Forbidden]
|
||||
```
|
||||
|
||||
| Key Permissions | Team Permissions | Result | Notes |
|
||||
|-----------------|------------------|--------|-------|
|
||||
| None | None | Key can access **all** agents | Open access by default when no restrictions are set |
|
||||
| `["agent-1", "agent-2"]` | None | Key can access `agent-1` and `agent-2` | Key uses its own permissions |
|
||||
| None | `["agent-1", "agent-3"]` | Key can access `agent-1` and `agent-3` | Key inherits team's permissions |
|
||||
| `["agent-1", "agent-2"]` | `["agent-1", "agent-3"]` | Key can access `agent-1` only | Intersection of both lists (most restrictive wins) |
|
||||
|
||||
## Viewing Permissions
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI">
|
||||
|
||||
1. Go to **Keys** or **Teams**
|
||||
2. Click into the key/team you want to view
|
||||
3. Agent permissions are displayed in the info view
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
```bash title="Get key info" showLineNumbers
|
||||
curl "http://localhost:4000/key/info?key=sk-your-key" \
|
||||
-H "Authorization: Bearer sk-master-key"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue