mirror of
https://github.com/BerriAI/litellm.git
synced 2026-09-22 00:31:44 +00:00
Merge branch 'perf/logging-early-return' into litellm_perf_ryan_staging
This commit is contained in:
 Ryan Crabbe
commit
e84f130413
521 changed files with 5849 additions and 1916 deletions
1
.gitignore
vendored
1
.gitignore
vendored
|
|
@ -2,6 +2,7 @@
|
|||
.venv
|
||||
.venv_policy_test
|
||||
.env
|
||||
.claude
|
||||
.newenv
|
||||
newenv/*
|
||||
litellm/proxy/myenv/*
|
||||
|
|
|
|||
274
docs/my-website/blog/claude_code_beta_headers/index.md
Normal file
274
docs/my-website/blog/claude_code_beta_headers/index.md
Normal file
|
|
@ -0,0 +1,274 @@
|
|||
---
|
||||
slug: claude_code_beta_headers
|
||||
title: "Claude Code - Managing Anthropic Beta Headers"
|
||||
date: 2026-02-16T10:00:00
|
||||
authors:
|
||||
- name: Sameer Kankute
|
||||
title: SWE @ LiteLLM (LLM Translation)
|
||||
url: https://www.linkedin.com/in/sameer-kankute/
|
||||
image_url: https://pbs.twimg.com/profile_images/2001352686994907136/ONgNuSk5_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
- name: Krrish Dholakia
|
||||
title: "CEO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
description: "How to manage and configure Anthropic beta headers with Claude Code in LiteLLM: filtering, mapping, and dynamic updates across providers."
|
||||
tags: [anthropic, claude, beta headers, configuration, liteLLM]
|
||||
hide_table_of_contents: false
|
||||
|
||||
---
|
||||
import Image from '@theme/IdealImage';
|
||||
|
||||
When using Claude Code with LiteLLM and non-Anthropic providers (Bedrock, Azure AI, Vertex AI), you need to ensure that only supported beta headers are sent to each provider. This guide explains how to add support for new beta headers or fix invalid beta header errors.
|
||||
|
||||
## What Are Beta Headers?
|
||||
|
||||
Anthropic uses beta headers to enable experimental features in Claude. When you use Claude Code, it may send beta headers like:
|
||||
|
||||
```
|
||||
anthropic-beta: prompt-caching-scope-2026-01-05,advanced-tool-use-2025-11-20
|
||||
```
|
||||
|
||||
However, not all providers support all Anthropic beta features. LiteLLM uses `anthropic_beta_headers_config.json` to manage which beta headers are supported by each provider.
|
||||
|
||||
## Common Error Message
|
||||
|
||||
```bash
|
||||
Error: The model returned the following errors: invalid beta flag
|
||||
```
|
||||
|
||||
## How LiteLLM Handles Beta Headers
|
||||
|
||||
LiteLLM uses a strict validation approach with a configuration file:
|
||||
|
||||
```
|
||||
litellm/litellm/anthropic_beta_headers_config.json
|
||||
```
|
||||
|
||||
This JSON file contains a **mapping** of beta headers for each provider:
|
||||
- **Keys**: Input beta header names (from Anthropic)
|
||||
- **Values**: Provider-specific header names (or `null` if unsupported)
|
||||
- **Validation**: Only headers present in the mapping with non-null values are forwarded
|
||||
|
||||
This enforces stricter validation than just filtering unsupported headers - headers must be explicitly defined to be allowed.
|
||||
|
||||
## Adding Support for a New Beta Header
|
||||
|
||||
When Anthropic releases a new beta feature, you need to add it to the configuration file for each provider.
|
||||
|
||||
### Step 1: Add the New Beta Header
|
||||
|
||||
Open `anthropic_beta_headers_config.json` and add the new header to each provider's mapping:
|
||||
|
||||
```json title="anthropic_beta_headers_config.json"
|
||||
{
|
||||
"description": "Mapping of Anthropic beta headers for each provider. Keys are input header names, values are provider-specific header names (or null if unsupported). Only headers present in mapping keys with non-null values can be forwarded.",
|
||||
"anthropic": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"new-feature-2026-03-01": "new-feature-2026-03-01",
|
||||
...
|
||||
},
|
||||
"azure_ai": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"new-feature-2026-03-01": "new-feature-2026-03-01",
|
||||
...
|
||||
},
|
||||
"bedrock_converse": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"new-feature-2026-03-01": null,
|
||||
...
|
||||
},
|
||||
"bedrock": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"new-feature-2026-03-01": null,
|
||||
...
|
||||
},
|
||||
"vertex_ai": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"new-feature-2026-03-01": null,
|
||||
...
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Key Points:**
|
||||
- **Supported headers**: Set the value to the provider-specific header name (often the same as the key)
|
||||
- **Unsupported headers**: Set the value to `null`
|
||||
- **Header transformations**: Some providers use different header names (e.g., Bedrock maps `advanced-tool-use-2025-11-20` to `tool-search-tool-2025-10-19`)
|
||||
- **Alphabetical order**: Keep headers sorted alphabetically for maintainability
|
||||
|
||||
### Step 2: Reload Configuration (No Restart Required!)
|
||||
|
||||
**Option 1: Dynamic Reload Without Restart**
|
||||
|
||||
Instead of restarting your application, you can dynamically reload the beta headers configuration using environment variables and API endpoints:
|
||||
|
||||
```bash
|
||||
# Set environment variable to fetch from remote URL (Do this if you want to point it to some other URL)
|
||||
export LITELLM_ANTHROPIC_BETA_HEADERS_URL="https://raw.githubusercontent.com/BerriAI/litellm/main/litellm/anthropic_beta_headers_config.json"
|
||||
|
||||
# Manually trigger reload via API (no restart needed!)
|
||||
curl -X POST "https://your-proxy-url/reload/anthropic_beta_headers" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
**Option 2: Schedule Automatic Reloads**
|
||||
|
||||
Set up automatic reloading to always stay up-to-date with the latest beta headers:
|
||||
|
||||
```bash
|
||||
# Reload configuration every 24 hours
|
||||
curl -X POST "https://your-proxy-url/schedule/anthropic_beta_headers_reload?hours=24" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
**Option 3: Traditional Restart**
|
||||
|
||||
If you prefer the traditional approach, restart your LiteLLM proxy or application:
|
||||
|
||||
```bash
|
||||
# If using LiteLLM proxy
|
||||
litellm --config config.yaml
|
||||
|
||||
# If using Python SDK
|
||||
# Just restart your Python application
|
||||
```
|
||||
|
||||
:::tip Zero-Downtime Updates
|
||||
With dynamic reloading, you can fix invalid beta header errors **without restarting your service**! This is especially useful in production environments where downtime is costly.
|
||||
|
||||
See [Auto Sync Anthropic Beta Headers](../proxy/sync_anthropic_beta_headers.md) for complete documentation.
|
||||
:::
|
||||
|
||||
## Fixing Invalid Beta Header Errors
|
||||
|
||||
If you encounter an "invalid beta flag" error, it means a beta header is being sent that the provider doesn't support.
|
||||
|
||||
### Step 1: Identify the Problematic Header
|
||||
|
||||
Check your logs to see which header is causing the issue:
|
||||
|
||||
```bash
|
||||
Error: The model returned the following errors: invalid beta flag: new-feature-2026-03-01
|
||||
```
|
||||
|
||||
### Step 2: Update the Config
|
||||
|
||||
Set the header value to `null` for that provider:
|
||||
|
||||
```json title="anthropic_beta_headers_config.json"
|
||||
{
|
||||
"bedrock_converse": {
|
||||
"new-feature-2026-03-01": null
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Step 3: Restart and Test
|
||||
|
||||
Restart your application and verify the header is now filtered out.
|
||||
|
||||
## Contributing a Fix to LiteLLM
|
||||
|
||||
Help the community by contributing your fix!
|
||||
|
||||
### What to Include in Your PR
|
||||
|
||||
1. **Update the config file**: Add the new beta header to `litellm/anthropic_beta_headers_config.json`
|
||||
2. **Test your changes**: Verify the header is correctly filtered/mapped for each provider
|
||||
3. **Documentation**: Include provider documentation links showing which headers are supported
|
||||
|
||||
### Example PR Description
|
||||
|
||||
```markdown
|
||||
## Add support for new-feature-2026-03-01 beta header
|
||||
|
||||
### Changes
|
||||
- Added `new-feature-2026-03-01` to anthropic_beta_headers_config.json
|
||||
- Set to `null` for bedrock_converse (unsupported)
|
||||
- Set to header name for anthropic, azure_ai (supported)
|
||||
|
||||
### Testing
|
||||
Tested with:
|
||||
- ✅ Anthropic: Header passed through correctly
|
||||
- ✅ Azure AI: Header passed through correctly
|
||||
- ✅ Bedrock Converse: Header filtered out (returns error without fix)
|
||||
|
||||
### References
|
||||
- Anthropic docs: [link]
|
||||
- AWS Bedrock docs: [link]
|
||||
```
|
||||
|
||||
|
||||
## How Beta Header Filtering Works
|
||||
|
||||
When you make a request through LiteLLM:
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant CC as Claude Code
|
||||
participant LP as LiteLLM
|
||||
participant Config as Beta Headers Config
|
||||
participant Provider as Provider (Bedrock/Azure/etc)
|
||||
|
||||
CC->>LP: Request with beta headers
|
||||
Note over CC,LP: anthropic-beta: header1,header2,header3
|
||||
|
||||
LP->>Config: Load header mapping for provider
|
||||
Config-->>LP: Returns mapping (header→value or null)
|
||||
|
||||
Note over LP: Validate & Transform:<br/>1. Check if header exists in mapping<br/>2. Filter out null values<br/>3. Map to provider-specific names
|
||||
|
||||
LP->>Provider: Request with filtered & mapped headers
|
||||
Note over LP,Provider: anthropic-beta: mapped-header2<br/>(header1, header3 filtered out)
|
||||
|
||||
Provider-->>LP: Success response
|
||||
LP-->>CC: Response
|
||||
```
|
||||
|
||||
### Filtering Rules
|
||||
|
||||
1. **Header must exist in mapping**: Unknown headers are filtered out
|
||||
2. **Header must have non-null value**: Headers with `null` values are filtered out
|
||||
3. **Header transformation**: Headers are mapped to provider-specific names (e.g., `advanced-tool-use-2025-11-20` → `tool-search-tool-2025-10-19` for Bedrock)
|
||||
|
||||
### Example
|
||||
|
||||
Request with headers:
|
||||
```
|
||||
anthropic-beta: advanced-tool-use-2025-11-20,computer-use-2025-01-24,unknown-header
|
||||
```
|
||||
|
||||
For Bedrock Converse:
|
||||
- ✅ `computer-use-2025-01-24` → `computer-use-2025-01-24` (supported, passed through)
|
||||
- ❌ `advanced-tool-use-2025-11-20` → filtered out (null value in config)
|
||||
- ❌ `unknown-header` → filtered out (not in config)
|
||||
|
||||
Result sent to Bedrock:
|
||||
```
|
||||
anthropic-beta: computer-use-2025-01-24
|
||||
```
|
||||
|
||||
## Dynamic Configuration Management (No Restart Required!)
|
||||
|
||||
### Environment Variables
|
||||
|
||||
Control how LiteLLM loads the beta headers configuration:
|
||||
|
||||
| Variable | Description | Default |
|
||||
|----------|-------------|---------|
|
||||
| `LITELLM_ANTHROPIC_BETA_HEADERS_URL` | URL to fetch config from | GitHub main branch |
|
||||
| `LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS` | Set to `True` to use local config only | `False` |
|
||||
|
||||
**Example: Use Custom Config URL**
|
||||
```bash
|
||||
export LITELLM_ANTHROPIC_BETA_HEADERS_URL="https://your-company.com/custom-beta-headers.json"
|
||||
```
|
||||
|
||||
**Example: Use Local Config Only (No Remote Fetching)**
|
||||
```bash
|
||||
export LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS=True
|
||||
```
|
||||
|
|
@ -185,7 +185,7 @@ curl --location 'http://0.0.0.0:4000/chat/completions' \
|
|||
model_list:
|
||||
- model_name: claude-opus-4-6
|
||||
litellm_params:
|
||||
model: bedrock/anthropic.claude-opus-4-6-v1:0
|
||||
model: bedrock/anthropic.claude-opus-4-6-v1
|
||||
aws_access_key_id: os.environ/AWS_ACCESS_KEY_ID
|
||||
aws_secret_access_key: os.environ/AWS_SECRET_ACCESS_KEY
|
||||
aws_region_name: us-east-1
|
||||
|
|
|
|||
|
|
@ -1,22 +1,121 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# OpenAI Agents SDK
|
||||
|
||||
The [OpenAI Agents SDK](https://github.com/openai/openai-agents-python) is a lightweight framework for building multi-agent workflows.
|
||||
It includes an official LiteLLM extension that lets you use any of the 100+ supported providers (Anthropic, Gemini, Mistral, Bedrock, etc.)
|
||||
Use OpenAI Agents SDK with any LLM provider through LiteLLM Proxy.
|
||||
|
||||
The [OpenAI Agents SDK](https://github.com/openai/openai-agents-python) is a lightweight framework for building multi-agent workflows. It includes an official LiteLLM extension that lets you use any of the 100+ supported providers.
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Install Dependencies
|
||||
|
||||
```bash
|
||||
pip install "openai-agents[litellm]"
|
||||
```
|
||||
|
||||
### 2. Add Model to Config
|
||||
|
||||
```yaml title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4o
|
||||
litellm_params:
|
||||
model: "openai/gpt-4o"
|
||||
api_key: "os.environ/OPENAI_API_KEY"
|
||||
|
||||
- model_name: claude-sonnet
|
||||
litellm_params:
|
||||
model: "anthropic/claude-3-5-sonnet-20241022"
|
||||
api_key: "os.environ/ANTHROPIC_API_KEY"
|
||||
|
||||
- model_name: gemini-pro
|
||||
litellm_params:
|
||||
model: "gemini/gemini-2.0-flash-exp"
|
||||
api_key: "os.environ/GEMINI_API_KEY"
|
||||
```
|
||||
|
||||
### 3. Start LiteLLM Proxy
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
### 4. Use with Proxy
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="Via Proxy">
|
||||
|
||||
```python
|
||||
from agents import Agent, Runner
|
||||
from agents.extensions.models.litellm_model import LitellmModel
|
||||
|
||||
# Point to LiteLLM proxy
|
||||
agent = Agent(
|
||||
name="Assistant",
|
||||
instructions="You are a helpful assistant.",
|
||||
model=LitellmModel(model="provider/model-name")
|
||||
model=LitellmModel(
|
||||
model="claude-sonnet", # Model from config.yaml
|
||||
api_key="sk-1234", # LiteLLM API key
|
||||
base_url="http://localhost:4000"
|
||||
)
|
||||
)
|
||||
|
||||
result = Runner.run_sync(agent, "your_prompt_here")
|
||||
print("Result:", result.final_output)
|
||||
result = await Runner.run(agent, "What is LiteLLM?")
|
||||
print(result.final_output)
|
||||
```
|
||||
|
||||
- [GitHub](https://github.com/openai/openai-agents-python)
|
||||
- [LiteLLM Extension Docs](https://openai.github.io/openai-agents-python/ref/extensions/litellm/)
|
||||
</TabItem>
|
||||
<TabItem value="direct" label="Direct (No Proxy)">
|
||||
|
||||
```python
|
||||
from agents import Agent, Runner
|
||||
from agents.extensions.models.litellm_model import LitellmModel
|
||||
|
||||
# Use any provider directly
|
||||
agent = Agent(
|
||||
name="Assistant",
|
||||
instructions="You are a helpful assistant.",
|
||||
model=LitellmModel(
|
||||
model="anthropic/claude-3-5-sonnet-20241022",
|
||||
api_key="your-anthropic-key"
|
||||
)
|
||||
)
|
||||
|
||||
result = await Runner.run(agent, "What is LiteLLM?")
|
||||
print(result.final_output)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Track Usage
|
||||
|
||||
Enable usage tracking to monitor token consumption:
|
||||
|
||||
```python
|
||||
from agents import Agent, ModelSettings
|
||||
from agents.extensions.models.litellm_model import LitellmModel
|
||||
|
||||
agent = Agent(
|
||||
name="Assistant",
|
||||
model=LitellmModel(model="claude-sonnet", api_key="sk-1234"),
|
||||
model_settings=ModelSettings(include_usage=True)
|
||||
)
|
||||
|
||||
result = await Runner.run(agent, "Hello")
|
||||
print(result.context_wrapper.usage) # Token counts
|
||||
```
|
||||
|
||||
## Environment Variables
|
||||
|
||||
| Variable | Value | Description |
|
||||
|----------|-------|-------------|
|
||||
| `LITELLM_BASE_URL` | `http://localhost:4000` | LiteLLM proxy URL |
|
||||
| `LITELLM_API_KEY` | `sk-1234` | Your LiteLLM API key |
|
||||
|
||||
## Related Resources
|
||||
|
||||
- [OpenAI Agents SDK Documentation](https://openai.github.io/openai-agents-python/)
|
||||
- [LiteLLM Extension Docs](https://openai.github.io/openai-agents-python/models/litellm/)
|
||||
- [LiteLLM Proxy Quick Start](../proxy/quick_start)
|
||||
|
|
|
|||
122
docs/my-website/docs/proxy/access_groups.md
Normal file
122
docs/my-website/docs/proxy/access_groups.md
Normal file
|
|
@ -0,0 +1,122 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Access Groups
|
||||
|
||||
Access Groups simplify how you define and manage resource access across your organization. Instead of configuring models, MCP servers, and agents separately on each key or team, you create one group that bundles the resources you want to grant, then attach that group to your keys or teams.
|
||||
|
||||
## Overview
|
||||
|
||||
**Access Groups** let you define a reusable set of allowed resources—models, MCP servers, and agents—in a single place. One group can grant access to all three resource types. Simply attach the group to a key or team, and they get access to everything defined in that group.
|
||||
|
||||
- **Unified resource control** – One group controls access to models, MCP servers, and agents together
|
||||
- **Reusable** – Define once, attach to many keys or teams
|
||||
- **Easy to maintain** – Update the group (add or remove resources) and all attached keys and teams automatically reflect the change
|
||||
- **Clear visibility** – See exactly which resources each group grants and which keys/teams use it
|
||||
|
||||
<Image img={require('../../img/ui_access_groups.png')} />
|
||||
|
||||
### How It Works
|
||||
|
||||
**Key concept:** Define resources in a group → Attach group to key or team → Key/team gets access to all resources in the group
|
||||
|
||||
| Resource Type | What the group controls |
|
||||
| --------------- | -------------------------------------------------------------------- |
|
||||
| **Models** | Which LLM models keys/teams can use (e.g., `gpt-4`, `claude-3-opus`) |
|
||||
| **MCP Servers** | Which MCP servers are available for tool calling |
|
||||
| **Agents** | Which agents can be invoked |
|
||||
|
||||
## How to Create and Use Access Groups in the UI
|
||||
|
||||
### 1. Navigate to Access Groups
|
||||
|
||||
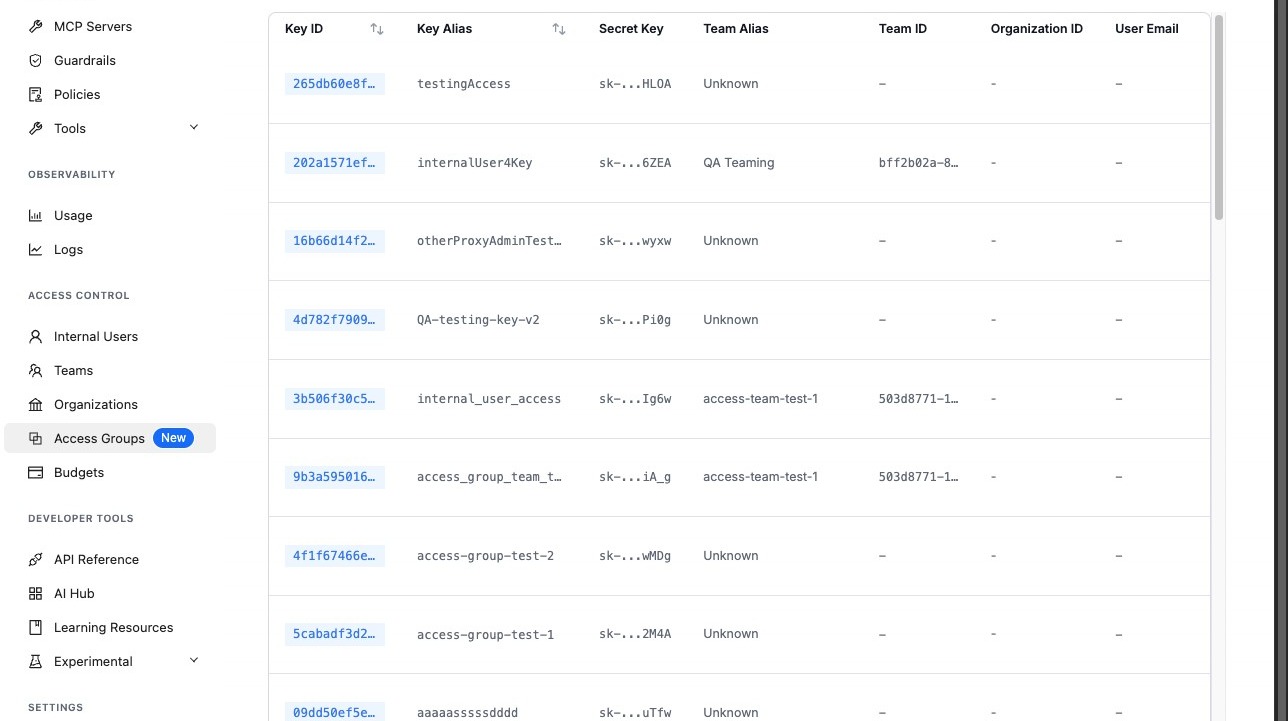
Go to the Admin UI (e.g. `http://localhost:4000/ui` or your `PROXY_BASE_URL/ui`) and click **Access Groups** in the sidebar.
|
||||
|
||||
|
||||
|
||||
### 2. Create an Access Group
|
||||
|
||||
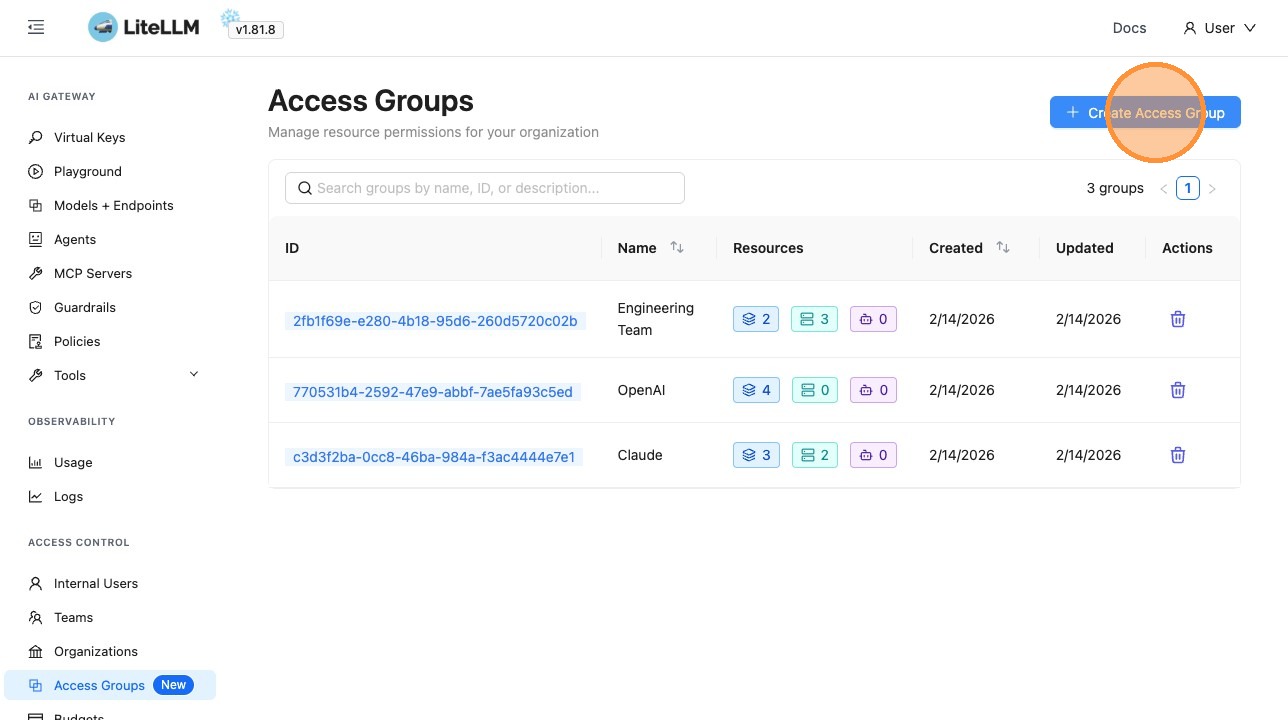
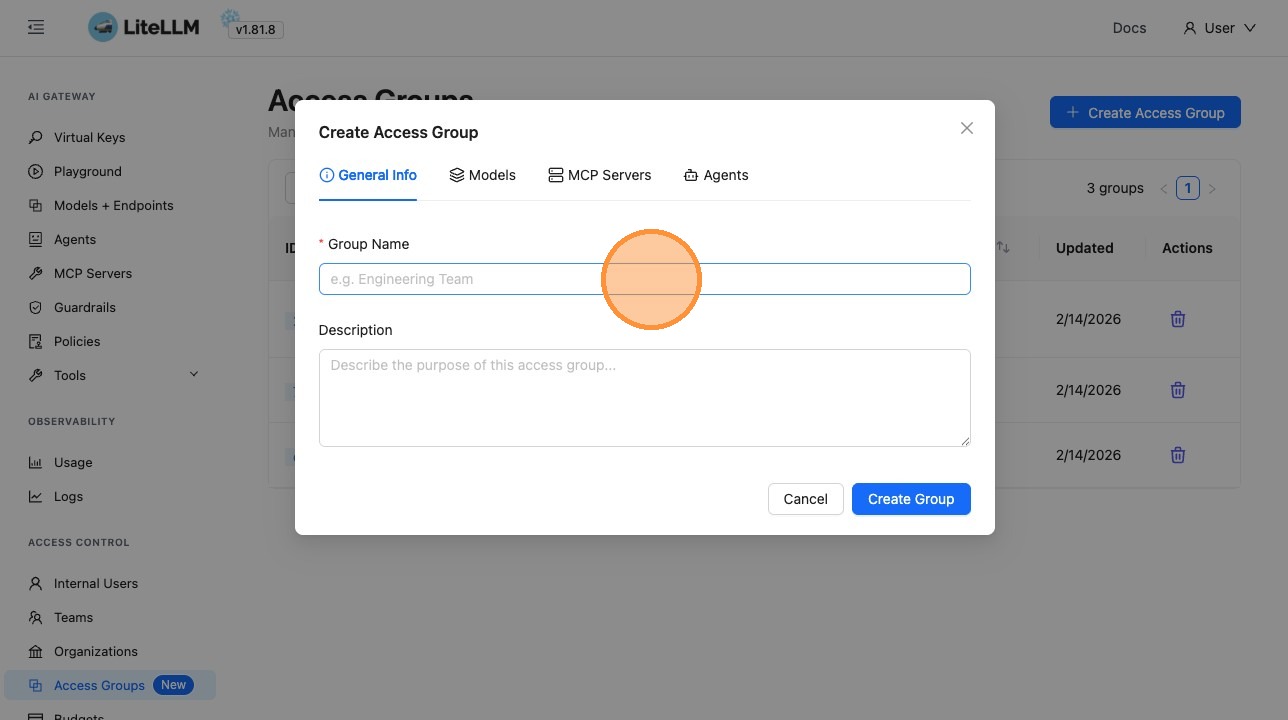
Click **Create Access Group** and give your group a name.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
### 3. Define Resources in the Group
|
||||
|
||||
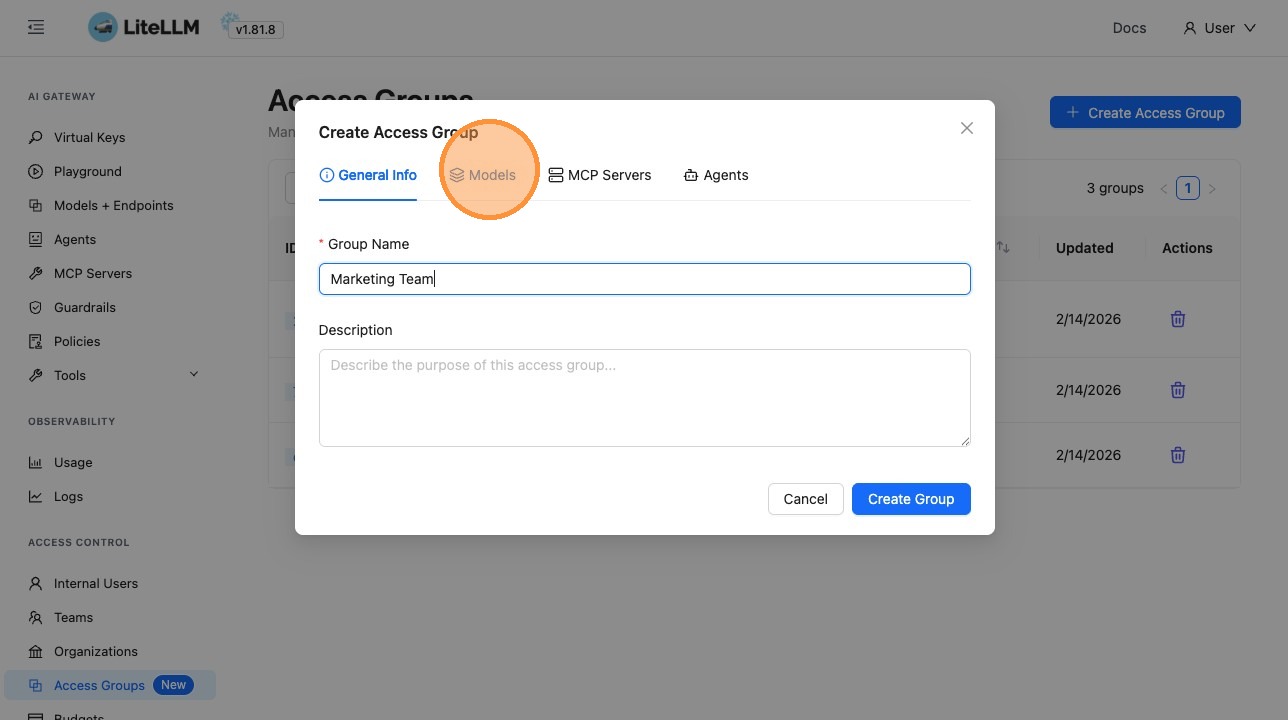
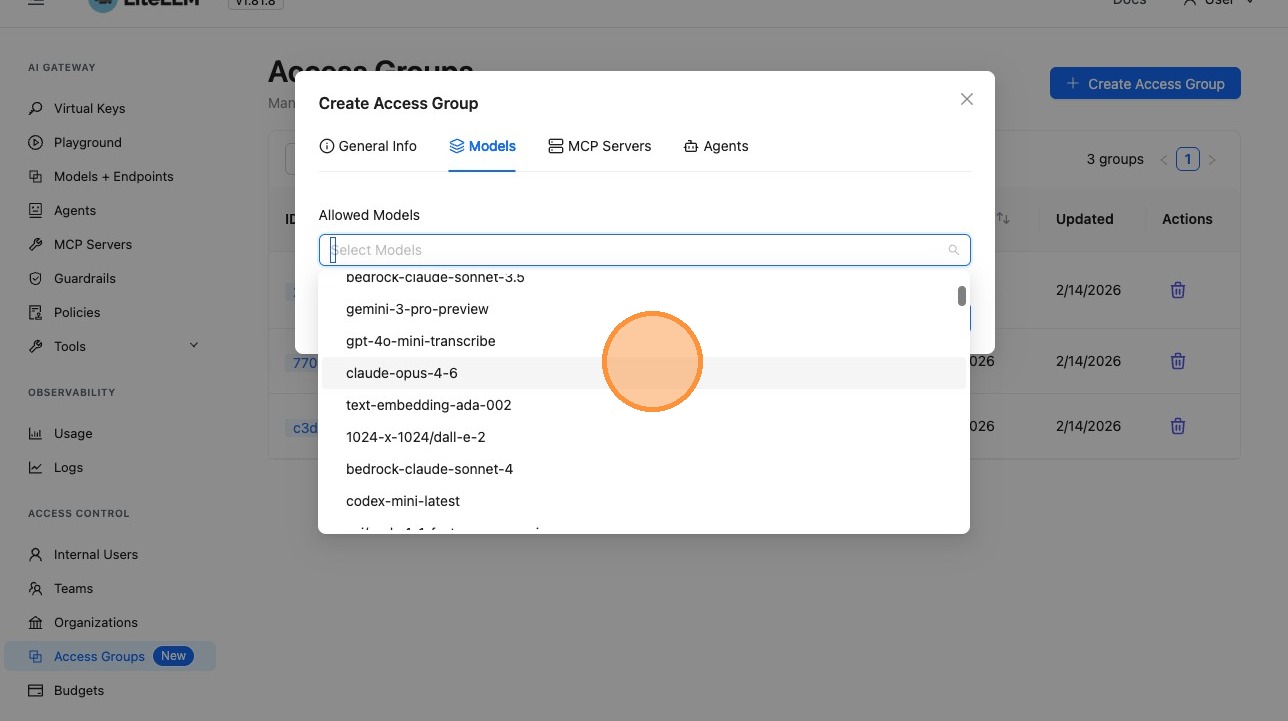
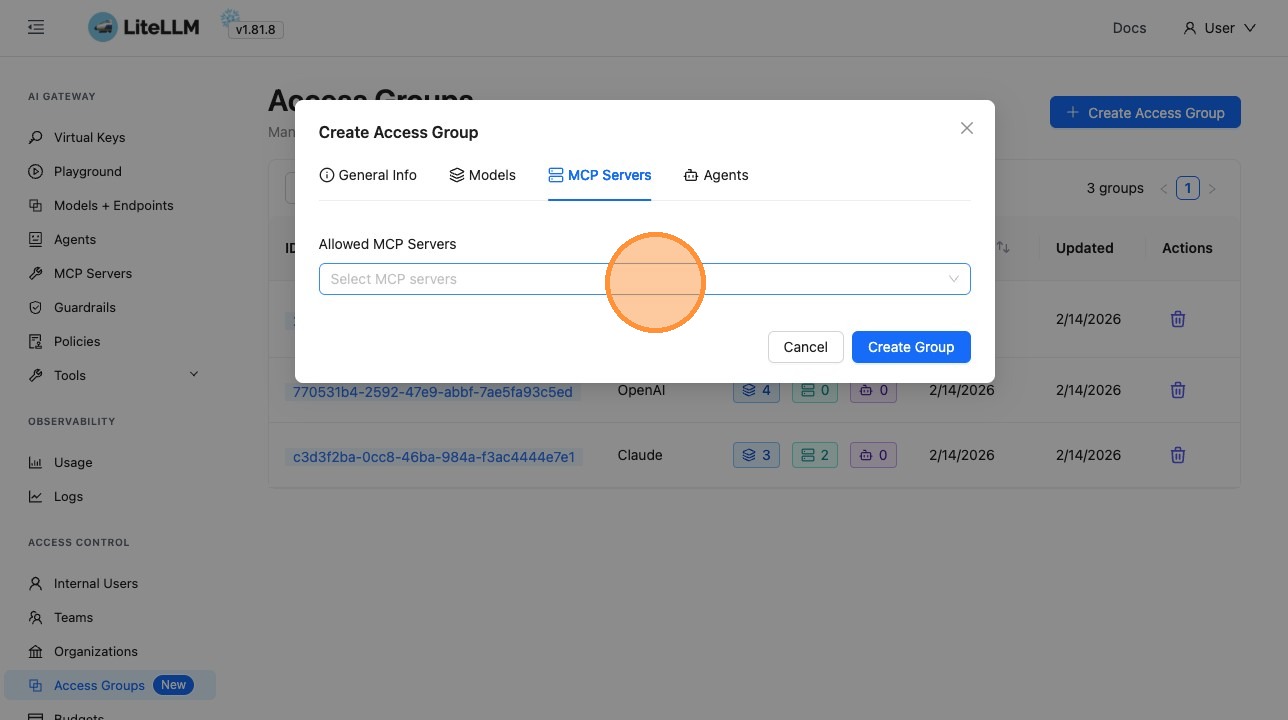
Use the tabs to select which models, MCP servers, and agents this group grants access to:
|
||||
|
||||
- **Models tab** – Select the LLM models
|
||||
- **MCP Servers tab** – Select MCP servers (for tool calling)
|
||||
- **Agents tab** – Select agents
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
### 4. Attach the Access Group to a Key
|
||||
|
||||
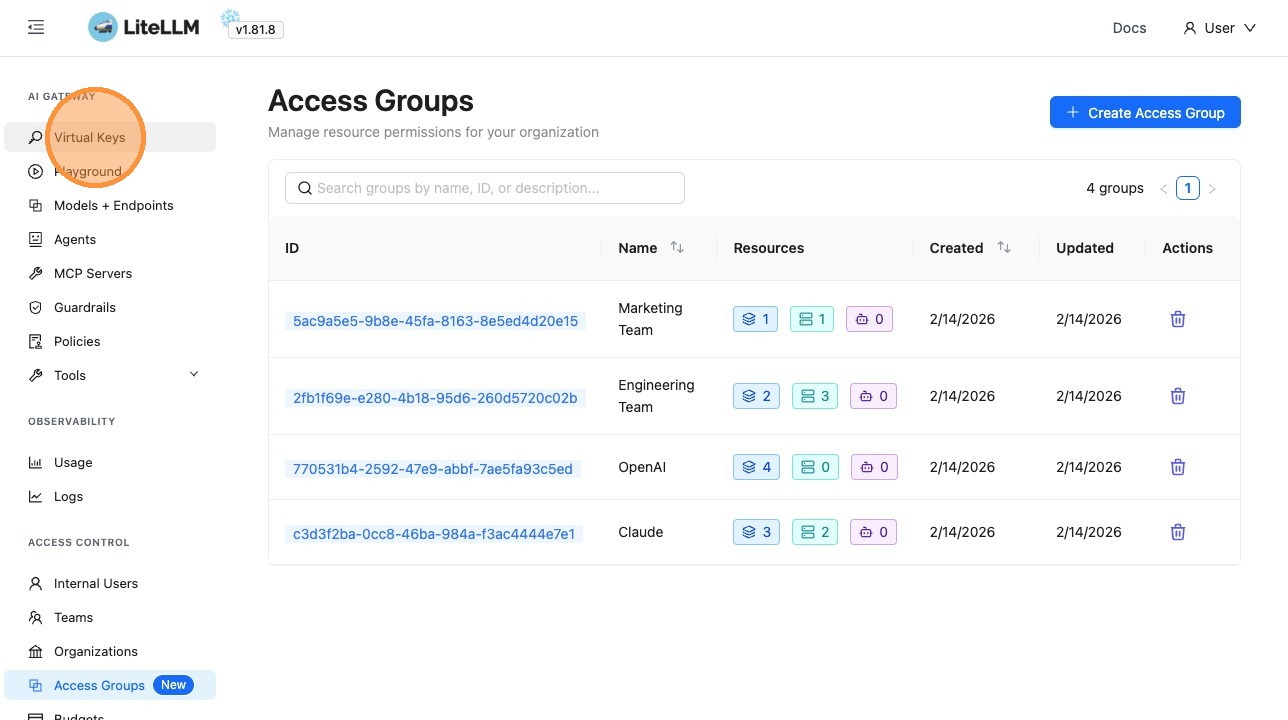
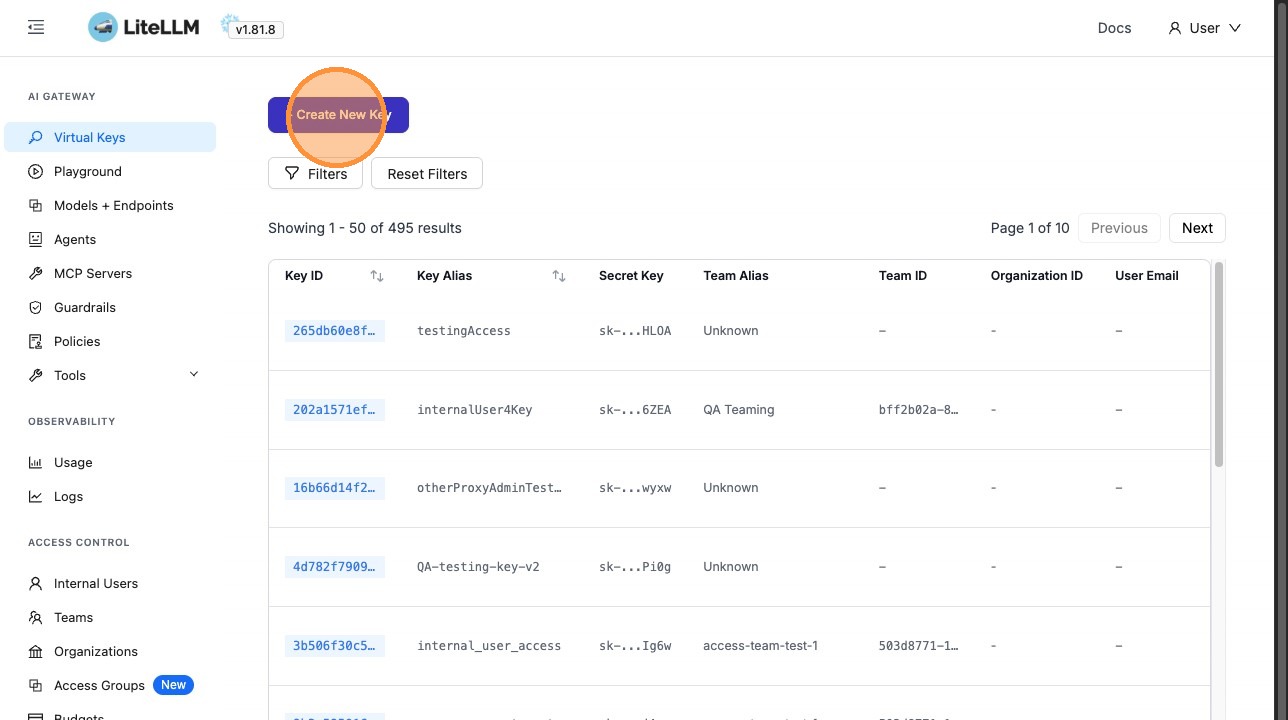
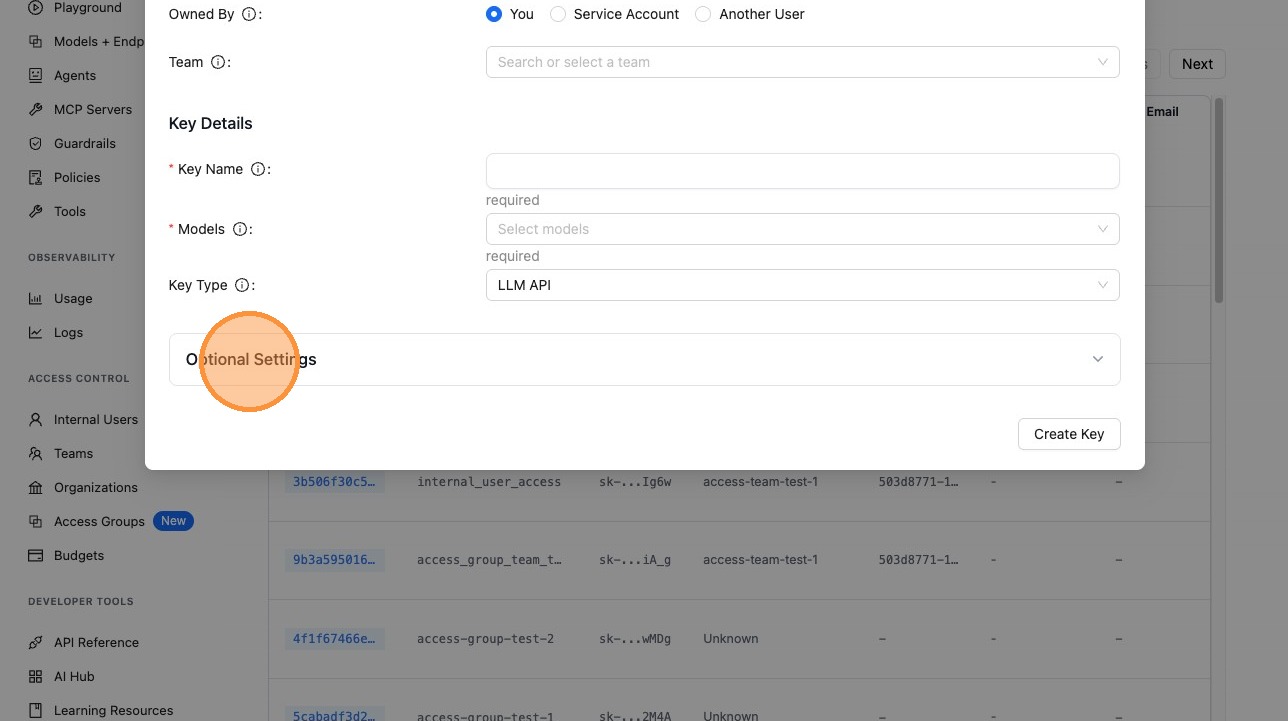
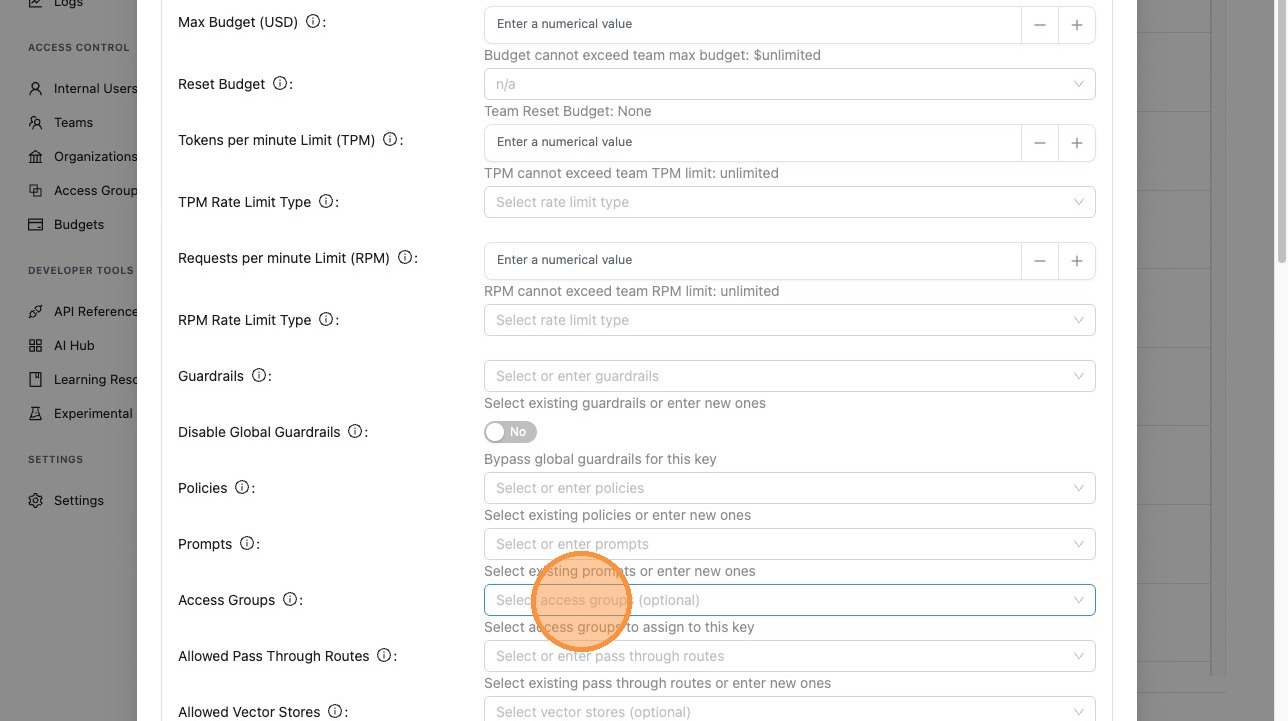
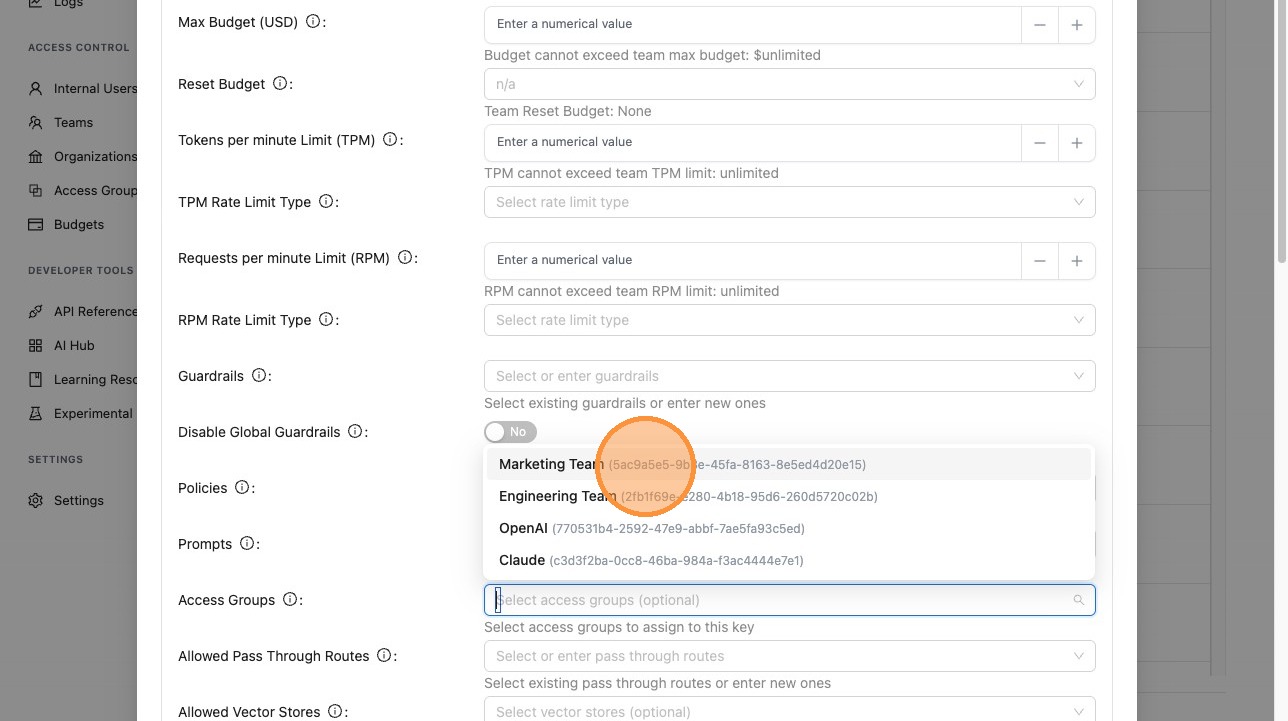
When creating or editing a virtual key, expand **Optional Settings** and select your Access Group. The key will inherit access to all models, MCP servers, and agents defined in that group.
|
||||
|
||||
1. Go to **Virtual Keys** and click **+ Create New Key**
|
||||
2. Expand **Optional Settings**
|
||||
3. In the Access Group field, select the group you created
|
||||
4. Save the key
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
### 5. Attach the Access Group to a Team
|
||||
|
||||
You can also attach an Access Group to a team when creating or editing the team. All keys associated with that team will then have access to the resources defined in the group.
|
||||
|
||||
## Use Cases
|
||||
|
||||
### Team-based Access
|
||||
|
||||
Create groups like "Engineering", "Data Science", or "Product" with the models, MCP servers, and agents each team needs. Attach the group to the team—no need to configure each resource on every key.
|
||||
|
||||
### Environment Separation
|
||||
|
||||
- **Production group** – Production models, approved MCP servers, and production agents
|
||||
- **Development group** – Cost-efficient models, experimental MCP tools, and dev agents
|
||||
|
||||
Attach the appropriate group to keys or teams based on environment.
|
||||
|
||||
### Simplified Onboarding
|
||||
|
||||
New developers get a key with an Access Group instead of manually configuring models, MCP servers, and agents. Add them to the right team or give them a key with the correct group.
|
||||
|
||||
### Centralized Updates
|
||||
|
||||
When you add a new model or MCP server to a group, every key and team attached to that group automatically gains access. Remove a resource from the group and it’s revoked everywhere at once.
|
||||
|
||||
## Access Group vs. Model Access Groups
|
||||
|
||||
LiteLLM has two related concepts:
|
||||
|
||||
| Feature | **Access Groups** (this page) | **Model Access Groups** |
|
||||
| ---------- | ----------------------------------------------------------------------- | ------------------------------------------------------- |
|
||||
| Definition | Define in the UI; one group can include models, MCP servers, and agents | Defined in config or via API; groups are model-centric |
|
||||
| Scope | Models + MCP servers + agents | Models only |
|
||||
| Attach to | Keys, teams | Keys, teams |
|
||||
| Use when | You want unified control over models, MCP, and agents from the UI | You need config-based or API-based model access control |
|
||||
|
||||
For config-based model access with `access_groups` in `model_info`, see [Model Access Groups](./model_access_groups.md).
|
||||
|
||||
## Related Documentation
|
||||
|
||||
- [Virtual Keys](./virtual_keys.md) – Creating and managing API keys
|
||||
- [Role-based Access Controls](./access_control.md) – Organizations, teams, and user roles
|
||||
- [Model Access Groups](./model_access_groups.md) – Config-based model access groups
|
||||
- [MCP Control](../mcp_control.md) – MCP server setup and access control
|
||||
|
|
@ -769,6 +769,7 @@ router_settings:
|
|||
| LITELM_ENVIRONMENT | Environment of LiteLLM Instance, used by logging services. Currently only used by DeepEval.
|
||||
| LITELLM_KEY_ROTATION_ENABLED | Enable auto-key rotation for LiteLLM (boolean). Default is false.
|
||||
| LITELLM_KEY_ROTATION_CHECK_INTERVAL_SECONDS | Interval in seconds for how often to run job that auto-rotates keys. Default is 86400 (24 hours).
|
||||
| LITELLM_KEY_ROTATION_GRACE_PERIOD | Duration to keep old key valid after rotation (e.g. "24h", "2d"). Default is empty (immediate revoke). Used for scheduled rotations and as fallback when not specified in regenerate request.
|
||||
| LITELLM_LICENSE | License key for LiteLLM usage
|
||||
| LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS | Set to `True` to use the local bundled Anthropic beta headers config only, disabling remote fetching. Default is `False`
|
||||
| LITELLM_LOCAL_MODEL_COST_MAP | Local configuration for model cost mapping in LiteLLM
|
||||
|
|
|
|||
|
|
@ -1338,6 +1338,7 @@ litellm_settings:
|
|||
s3_aws_secret_access_key: os.environ/AWS_SECRET_ACCESS_KEY # AWS Secret Access Key for S3
|
||||
s3_path: my-test-path # [OPTIONAL] set path in bucket you want to write logs to
|
||||
s3_endpoint_url: https://s3.amazonaws.com # [OPTIONAL] S3 endpoint URL, if you want to use Backblaze/cloudflare s3 buckets
|
||||
s3_use_virtual_hosted_style: false # [OPTIONAL] use virtual-hosted-style URLs (bucket.endpoint/key) instead of path-style (endpoint/bucket/key). Useful for S3-compatible services like MinIO
|
||||
s3_strip_base64_files: false # [OPTIONAL] remove base64 files before storing in s3
|
||||
```
|
||||
|
||||
|
|
|
|||
|
|
@ -549,11 +549,14 @@ curl 'http://localhost:4000/key/sk-1234/regenerate' \
|
|||
"models": [
|
||||
"gpt-4",
|
||||
"gpt-3.5-turbo"
|
||||
]
|
||||
],
|
||||
"grace_period": "48h"
|
||||
}'
|
||||
|
||||
```
|
||||
|
||||
**Grace period (optional)**: Set `grace_period` (e.g. `"24h"`, `"2d"`, `"1w"`) to keep the old key valid for a transitional period. Both old and new keys work until the grace period elapses, enabling seamless cutover without production downtime. Omitted or empty = immediate revoke. Can also be set via `LITELLM_KEY_ROTATION_GRACE_PERIOD` env var for scheduled rotations.
|
||||
|
||||
**Read More**
|
||||
|
||||
- [Write rotated keys to secrets manager](https://docs.litellm.ai/docs/secret#aws-secret-manager)
|
||||
|
|
@ -640,11 +643,13 @@ Set these environment variables when starting the proxy:
|
|||
|----------|-------------|---------|
|
||||
| `LITELLM_KEY_ROTATION_ENABLED` | Enable the rotation worker | `false` |
|
||||
| `LITELLM_KEY_ROTATION_CHECK_INTERVAL_SECONDS` | How often to scan for keys to rotate (in seconds) | `86400` (24 hours) |
|
||||
| `LITELLM_KEY_ROTATION_GRACE_PERIOD` | Duration to keep old key valid after rotation (e.g. `24h`, `2d`) | `""` (immediate revoke) |
|
||||
|
||||
**Example:**
|
||||
```bash
|
||||
export LITELLM_KEY_ROTATION_ENABLED=true
|
||||
export LITELLM_KEY_ROTATION_CHECK_INTERVAL_SECONDS=3600 # Check every hour
|
||||
export LITELLM_KEY_ROTATION_GRACE_PERIOD=48h # Keep old key valid for 48h during cutover
|
||||
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
|
|
|||
BIN
docs/my-website/img/ui_access_groups.png
Normal file
BIN
docs/my-website/img/ui_access_groups.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 338 KiB |
|
|
@ -46,8 +46,15 @@ pip install litellm==1.81.12.rc1
|
|||
- **Guardrail Action Builder** - [Build and customize guardrail policy flows with the new action-builder UI and conditional execution support](../../docs/proxy/guardrails/policy_templates)
|
||||
- **MCP OAuth2 M2M + Tracing** - [Add machine-to-machine OAuth2 support for MCP servers and OpenTelemetry tracing for MCP calls through AI Gateway](../../docs/mcp)
|
||||
- **Responses API `shell` Tool & `context_management` support** - [Server-side context management (compaction) and Shell tool support for the OpenAI Responses API](../../docs/response_api)
|
||||
- **Access Groups** - [Create access groups to manage model, MCP server, and agent access across teams and keys](../../docs/proxy/model_access_groups)
|
||||
- **Access Groups** - [Create access groups to manage model, MCP server, and agent access across teams and keys](../../docs/proxy/access_groups)
|
||||
- **50+ New Bedrock Regional Model Entries** - DeepSeek V3.2, MiniMax M2.1, Kimi K2.5, Qwen3 Coder Next, and NVIDIA Nemotron Nano across multiple regions
|
||||
- **Add Semgrep & fix OOMs** - [Static analysis rules and out-of-memory fixes](#add-semgrep--fix-ooms) - [PR #20912](https://github.com/BerriAI/litellm/pull/20912)
|
||||
|
||||
---
|
||||
|
||||
## Add Semgrep & fix OOMs
|
||||
|
||||
This release fixes out-of-memory (OOM) risks from unbounded `asyncio.Queue()` usage. Log queues (e.g. GCS bucket) and DB spend-update queues were previously unbounded and could grow without limit under load. They now use a configurable max size (`LITELLM_ASYNCIO_QUEUE_MAXSIZE`, default 1000); when full, queues flush immediately to make room instead of growing memory. A Semgrep rule (`.semgrep/rules/python/unbounded-memory.yml`) was added to flag similar unbounded-memory patterns in future code. [PR #20912](https://github.com/BerriAI/litellm/pull/20912)
|
||||
|
||||
---
|
||||
|
||||
|
|
@ -57,6 +64,12 @@ This release adds a visual action builder for guardrail policies with conditiona
|
|||
|
||||

|
||||
|
||||
### Access Groups
|
||||
|
||||
Access Groups simplify defining resource access across your organization. One group can grant access to models, MCP servers, and agents—simply attach it to a key or team. Create groups in the Admin UI, define which resources each group includes, then assign the group when creating keys or teams. Updates to a group apply automatically to all attached keys and teams.
|
||||
|
||||
<Image img={require('../img/ui_access_groups.png')} />
|
||||
|
||||
## New Providers and Endpoints
|
||||
|
||||
### New Providers (2 new providers)
|
||||
|
|
|
|||
|
|
@ -176,6 +176,7 @@ const sidebars = {
|
|||
"tutorials/copilotkit_sdk",
|
||||
"tutorials/google_adk",
|
||||
"tutorials/livekit_xai_realtime",
|
||||
"projects/openai-agents"
|
||||
]
|
||||
},
|
||||
|
||||
|
|
@ -467,6 +468,7 @@ const sidebars = {
|
|||
"proxy/model_access_guide",
|
||||
"proxy/model_access",
|
||||
"proxy/model_access_groups",
|
||||
"proxy/access_groups",
|
||||
"proxy/team_model_add"
|
||||
]
|
||||
},
|
||||
|
|
|
|||
|
|
@ -4,7 +4,7 @@ Polls LiteLLM_ManagedObjectTable to check if the batch job is complete, and if t
|
|||
|
||||
from litellm._uuid import uuid
|
||||
from datetime import datetime
|
||||
from typing import TYPE_CHECKING, Optional, cast
|
||||
from typing import TYPE_CHECKING, Optional
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
|
||||
|
|
@ -35,14 +35,11 @@ class CheckBatchCost:
|
|||
- if not, return False
|
||||
- if so, return True
|
||||
"""
|
||||
from litellm_enterprise.proxy.hooks.managed_files import (
|
||||
_PROXY_LiteLLMManagedFiles,
|
||||
)
|
||||
|
||||
from litellm.batches.batch_utils import (
|
||||
_get_file_content_as_dictionary,
|
||||
calculate_batch_cost_and_usage,
|
||||
)
|
||||
from litellm.files.main import afile_content
|
||||
from litellm.litellm_core_utils.get_llm_provider_logic import get_llm_provider
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLogging
|
||||
from litellm.proxy.openai_files_endpoints.common_utils import (
|
||||
|
|
@ -102,27 +99,29 @@ class CheckBatchCost:
|
|||
continue
|
||||
|
||||
## RETRIEVE THE BATCH JOB OUTPUT FILE
|
||||
managed_files_obj = cast(
|
||||
Optional[_PROXY_LiteLLMManagedFiles],
|
||||
self.proxy_logging_obj.get_proxy_hook("managed_files"),
|
||||
)
|
||||
if (
|
||||
response.status == "completed"
|
||||
and response.output_file_id is not None
|
||||
and managed_files_obj is not None
|
||||
):
|
||||
verbose_proxy_logger.info(
|
||||
f"Batch ID: {batch_id} is complete, tracking cost and usage"
|
||||
)
|
||||
# track cost
|
||||
model_file_id_mapping = {
|
||||
response.output_file_id: {model_id: response.output_file_id}
|
||||
}
|
||||
_file_content = await managed_files_obj.afile_content(
|
||||
file_id=response.output_file_id,
|
||||
litellm_parent_otel_span=None,
|
||||
llm_router=self.llm_router,
|
||||
model_file_id_mapping=model_file_id_mapping,
|
||||
|
||||
# This background job runs as default_user_id, so going through the HTTP endpoint
|
||||
# would trigger check_managed_file_id_access and get 403. Instead, extract the raw
|
||||
# provider file ID and call afile_content directly with deployment credentials.
|
||||
raw_output_file_id = response.output_file_id
|
||||
decoded = _is_base64_encoded_unified_file_id(raw_output_file_id)
|
||||
if decoded:
|
||||
try:
|
||||
raw_output_file_id = decoded.split("llm_output_file_id,")[1].split(";")[0]
|
||||
except (IndexError, AttributeError):
|
||||
pass
|
||||
|
||||
credentials = self.llm_router.get_deployment_credentials_with_provider(model_id) or {}
|
||||
_file_content = await afile_content(
|
||||
file_id=raw_output_file_id,
|
||||
**credentials,
|
||||
)
|
||||
|
||||
file_content_as_dict = _get_file_content_as_dictionary(
|
||||
|
|
@ -143,11 +142,15 @@ class CheckBatchCost:
|
|||
custom_llm_provider=custom_llm_provider,
|
||||
)
|
||||
|
||||
# Pass deployment model_info so custom batch pricing
|
||||
# (input_cost_per_token_batches etc.) is used for cost calc
|
||||
deployment_model_info = deployment_info.model_info.model_dump() if deployment_info.model_info else {}
|
||||
batch_cost, batch_usage, batch_models = (
|
||||
await calculate_batch_cost_and_usage(
|
||||
file_content_dictionary=file_content_as_dict,
|
||||
custom_llm_provider=llm_provider, # type: ignore
|
||||
model_name=model_name,
|
||||
model_info=deployment_model_info,
|
||||
)
|
||||
)
|
||||
logging_obj = LiteLLMLogging(
|
||||
|
|
|
|||
|
|
@ -230,12 +230,14 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
|
||||
if managed_file:
|
||||
return managed_file.created_by == user_id
|
||||
return False
|
||||
raise HTTPException(
|
||||
status_code=404,
|
||||
detail=f"File not found: {unified_file_id}",
|
||||
)
|
||||
|
||||
async def can_user_call_unified_object_id(
|
||||
self, unified_object_id: str, user_api_key_dict: UserAPIKeyAuth
|
||||
) -> bool:
|
||||
## check if the user has access to the unified object id
|
||||
## check if the user has access to the unified object id
|
||||
user_id = user_api_key_dict.user_id
|
||||
managed_object = (
|
||||
|
|
@ -246,7 +248,10 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
|
||||
if managed_object:
|
||||
return managed_object.created_by == user_id
|
||||
return True # don't raise error if managed object is not found
|
||||
raise HTTPException(
|
||||
status_code=404,
|
||||
detail=f"Object not found: {unified_object_id}",
|
||||
)
|
||||
|
||||
async def list_user_batches(
|
||||
self,
|
||||
|
|
@ -911,15 +916,22 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
)
|
||||
setattr(response, file_attr, unified_file_id)
|
||||
|
||||
# Fetch the actual file object from the provider
|
||||
# Use llm_router credentials when available. Without credentials,
|
||||
# Azure and other auth-required providers return 500/401.
|
||||
file_object = None
|
||||
try:
|
||||
# Use litellm to retrieve the file object from the provider
|
||||
from litellm import afile_retrieve
|
||||
file_object = await afile_retrieve(
|
||||
custom_llm_provider=model_name.split("/")[0] if model_name and "/" in model_name else "openai",
|
||||
file_id=original_file_id
|
||||
)
|
||||
from litellm.proxy.proxy_server import llm_router as _llm_router
|
||||
if _llm_router is not None and model_id:
|
||||
_creds = _llm_router.get_deployment_credentials_with_provider(model_id) or {}
|
||||
file_object = await litellm.afile_retrieve(
|
||||
file_id=original_file_id,
|
||||
**_creds,
|
||||
)
|
||||
else:
|
||||
file_object = await litellm.afile_retrieve(
|
||||
custom_llm_provider=model_name.split("/")[0] if model_name and "/" in model_name else "openai",
|
||||
file_id=original_file_id,
|
||||
)
|
||||
verbose_logger.debug(
|
||||
f"Successfully retrieved file object for {file_attr}={original_file_id}"
|
||||
)
|
||||
|
|
@ -1004,7 +1016,10 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
raise Exception(f"LiteLLM Managed File object with id={file_id} not found")
|
||||
|
||||
# Case 2: Managed file and the file object exists in the database
|
||||
# The stored file_object has the raw provider ID. Replace with the unified ID
|
||||
# so callers see a consistent ID (matching Case 3 which does response.id = file_id).
|
||||
if stored_file_object and stored_file_object.file_object:
|
||||
stored_file_object.file_object.id = file_id
|
||||
return stored_file_object.file_object
|
||||
|
||||
# Case 3: Managed file exists in the database but not the file object (for. e.g the batch task might not have run)
|
||||
|
|
|
|||
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.40-py3-none-any.whl
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.40-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.40.tar.gz
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.40.tar.gz
vendored
Normal file
Binary file not shown.
|
|
@ -0,0 +1,19 @@
|
|||
-- CreateTable
|
||||
CREATE TABLE "LiteLLM_DeprecatedVerificationToken" (
|
||||
"id" TEXT NOT NULL,
|
||||
"token" TEXT NOT NULL,
|
||||
"active_token_id" TEXT NOT NULL,
|
||||
"revoke_at" TIMESTAMP(3) NOT NULL,
|
||||
"created_at" TIMESTAMP(3) NOT NULL DEFAULT CURRENT_TIMESTAMP,
|
||||
|
||||
CONSTRAINT "LiteLLM_DeprecatedVerificationToken_pkey" PRIMARY KEY ("id")
|
||||
);
|
||||
|
||||
-- CreateIndex
|
||||
CREATE UNIQUE INDEX "LiteLLM_DeprecatedVerificationToken_token_key" ON "LiteLLM_DeprecatedVerificationToken"("token");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeprecatedVerificationToken_token_revoke_at_idx" ON "LiteLLM_DeprecatedVerificationToken"("token", "revoke_at");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeprecatedVerificationToken_revoke_at_idx" ON "LiteLLM_DeprecatedVerificationToken"("revoke_at");
|
||||
|
|
@ -0,0 +1,2 @@
|
|||
-- This is an empty migration.
|
||||
|
||||
|
|
@ -325,6 +325,19 @@ model LiteLLM_VerificationToken {
|
|||
@@index([budget_reset_at, expires])
|
||||
}
|
||||
|
||||
// Deprecated keys during grace period - allows old key to work until revoke_at
|
||||
model LiteLLM_DeprecatedVerificationToken {
|
||||
id String @id @default(uuid())
|
||||
token String // Hashed old key
|
||||
active_token_id String // Current token hash in LiteLLM_VerificationToken
|
||||
revoke_at DateTime // When the old key stops working
|
||||
created_at DateTime @default(now()) @map("created_at")
|
||||
|
||||
@@unique([token])
|
||||
@@index([token, revoke_at])
|
||||
@@index([revoke_at])
|
||||
}
|
||||
|
||||
// Audit table for deleted keys - preserves spend and key information for historical tracking
|
||||
model LiteLLM_DeletedVerificationToken {
|
||||
id String @id @default(uuid())
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "litellm-proxy-extras"
|
||||
version = "0.4.39"
|
||||
version = "0.4.40"
|
||||
description = "Additional files for the LiteLLM Proxy. Reduces the size of the main litellm package."
|
||||
authors = ["BerriAI"]
|
||||
readme = "README.md"
|
||||
|
|
@ -22,7 +22,7 @@ requires = ["poetry-core"]
|
|||
build-backend = "poetry.core.masonry.api"
|
||||
|
||||
[tool.commitizen]
|
||||
version = "0.4.39"
|
||||
version = "0.4.40"
|
||||
version_files = [
|
||||
"pyproject.toml:version",
|
||||
"../requirements.txt:litellm-proxy-extras==",
|
||||
|
|
|
|||
|
|
@ -312,10 +312,12 @@ class ServiceLogging(CustomLogger):
|
|||
_duration, type(_duration)
|
||||
)
|
||||
) # invalid _duration value
|
||||
# Batch polling callbacks (check_batch_cost) don't include call_type in kwargs.
|
||||
# Use .get() to avoid KeyError.
|
||||
await self.async_service_success_hook(
|
||||
service=ServiceTypes.LITELLM,
|
||||
duration=_duration,
|
||||
call_type=kwargs["call_type"],
|
||||
call_type=kwargs.get("call_type", "unknown")
|
||||
)
|
||||
except Exception as e:
|
||||
raise e
|
||||
|
|
|
|||
|
|
@ -8,7 +8,7 @@ import litellm
|
|||
from litellm._logging import verbose_logger
|
||||
from litellm._uuid import uuid
|
||||
from litellm.types.llms.openai import Batch
|
||||
from litellm.types.utils import CallTypes, ModelResponse, Usage
|
||||
from litellm.types.utils import CallTypes, ModelInfo, ModelResponse, Usage
|
||||
from litellm.utils import token_counter
|
||||
|
||||
|
||||
|
|
@ -16,14 +16,22 @@ async def calculate_batch_cost_and_usage(
|
|||
file_content_dictionary: List[dict],
|
||||
custom_llm_provider: Literal["openai", "azure", "vertex_ai", "hosted_vllm", "anthropic"],
|
||||
model_name: Optional[str] = None,
|
||||
model_info: Optional[ModelInfo] = None,
|
||||
) -> Tuple[float, Usage, List[str]]:
|
||||
"""
|
||||
Calculate the cost and usage of a batch
|
||||
Calculate the cost and usage of a batch.
|
||||
|
||||
Args:
|
||||
model_info: Optional deployment-level model info with custom batch
|
||||
pricing. Threaded through to batch_cost_calculator so that
|
||||
deployment-specific pricing (e.g. input_cost_per_token_batches)
|
||||
is used instead of the global cost map.
|
||||
"""
|
||||
batch_cost = _batch_cost_calculator(
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
file_content_dictionary=file_content_dictionary,
|
||||
model_name=model_name,
|
||||
model_info=model_info,
|
||||
)
|
||||
batch_usage = _get_batch_job_total_usage_from_file_content(
|
||||
file_content_dictionary=file_content_dictionary,
|
||||
|
|
@ -94,6 +102,7 @@ def _batch_cost_calculator(
|
|||
file_content_dictionary: List[dict],
|
||||
custom_llm_provider: Literal["openai", "azure", "vertex_ai", "hosted_vllm", "anthropic"] = "openai",
|
||||
model_name: Optional[str] = None,
|
||||
model_info: Optional[ModelInfo] = None,
|
||||
) -> float:
|
||||
"""
|
||||
Calculate the cost of a batch based on the output file id
|
||||
|
|
@ -108,6 +117,7 @@ def _batch_cost_calculator(
|
|||
total_cost = _get_batch_job_cost_from_file_content(
|
||||
file_content_dictionary=file_content_dictionary,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
model_info=model_info,
|
||||
)
|
||||
verbose_logger.debug("total_cost=%s", total_cost)
|
||||
return total_cost
|
||||
|
|
@ -290,10 +300,13 @@ def _get_file_content_as_dictionary(file_content: bytes) -> List[dict]:
|
|||
def _get_batch_job_cost_from_file_content(
|
||||
file_content_dictionary: List[dict],
|
||||
custom_llm_provider: Literal["openai", "azure", "vertex_ai", "hosted_vllm", "anthropic"] = "openai",
|
||||
model_info: Optional[ModelInfo] = None,
|
||||
) -> float:
|
||||
"""
|
||||
Get the cost of a batch job from the file content
|
||||
"""
|
||||
from litellm.cost_calculator import batch_cost_calculator
|
||||
|
||||
try:
|
||||
total_cost: float = 0.0
|
||||
# parse the file content as json
|
||||
|
|
@ -303,11 +316,22 @@ def _get_batch_job_cost_from_file_content(
|
|||
for _item in file_content_dictionary:
|
||||
if _batch_response_was_successful(_item):
|
||||
_response_body = _get_response_from_batch_job_output_file(_item)
|
||||
total_cost += litellm.completion_cost(
|
||||
completion_response=_response_body,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
call_type=CallTypes.aretrieve_batch.value,
|
||||
)
|
||||
if model_info is not None:
|
||||
usage = _get_batch_job_usage_from_response_body(_response_body)
|
||||
model = _response_body.get("model", "")
|
||||
prompt_cost, completion_cost = batch_cost_calculator(
|
||||
usage=usage,
|
||||
model=model,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
model_info=model_info,
|
||||
)
|
||||
total_cost += prompt_cost + completion_cost
|
||||
else:
|
||||
total_cost += litellm.completion_cost(
|
||||
completion_response=_response_body,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
call_type=CallTypes.aretrieve_batch.value,
|
||||
)
|
||||
verbose_logger.debug("total_cost=%s", total_cost)
|
||||
return total_cost
|
||||
except Exception as e:
|
||||
|
|
|
|||
|
|
@ -319,6 +319,9 @@ NON_LLM_CONNECTION_TIMEOUT = int(
|
|||
MAX_EXCEPTION_MESSAGE_LENGTH = int(os.getenv("MAX_EXCEPTION_MESSAGE_LENGTH", 2000))
|
||||
MAX_STRING_LENGTH_PROMPT_IN_DB = int(os.getenv("MAX_STRING_LENGTH_PROMPT_IN_DB", 2048))
|
||||
BEDROCK_MAX_POLICY_SIZE = int(os.getenv("BEDROCK_MAX_POLICY_SIZE", 75))
|
||||
BEDROCK_MIN_THINKING_BUDGET_TOKENS = int(
|
||||
os.getenv("BEDROCK_MIN_THINKING_BUDGET_TOKENS", 1024)
|
||||
)
|
||||
REPLICATE_POLLING_DELAY_SECONDS = float(
|
||||
os.getenv("REPLICATE_POLLING_DELAY_SECONDS", 0.5)
|
||||
)
|
||||
|
|
@ -1258,6 +1261,9 @@ LITELLM_KEY_ROTATION_ENABLED = os.getenv("LITELLM_KEY_ROTATION_ENABLED", "false"
|
|||
LITELLM_KEY_ROTATION_CHECK_INTERVAL_SECONDS = int(
|
||||
os.getenv("LITELLM_KEY_ROTATION_CHECK_INTERVAL_SECONDS", 86400)
|
||||
) # 24 hours default
|
||||
LITELLM_KEY_ROTATION_GRACE_PERIOD: str = os.getenv(
|
||||
"LITELLM_KEY_ROTATION_GRACE_PERIOD", ""
|
||||
) # Duration to keep old key valid after rotation (e.g. "24h", "2d"); empty = immediate revoke (default)
|
||||
UI_SESSION_TOKEN_TEAM_ID = "litellm-dashboard"
|
||||
LITELLM_PROXY_ADMIN_NAME = "default_user_id"
|
||||
|
||||
|
|
|
|||
|
|
@ -1896,9 +1896,16 @@ def batch_cost_calculator(
|
|||
usage: Usage,
|
||||
model: str,
|
||||
custom_llm_provider: Optional[str] = None,
|
||||
model_info: Optional[ModelInfo] = None,
|
||||
) -> Tuple[float, float]:
|
||||
"""
|
||||
Calculate the cost of a batch job
|
||||
Calculate the cost of a batch job.
|
||||
|
||||
Args:
|
||||
model_info: Optional deployment-level model info containing custom
|
||||
batch pricing (e.g. input_cost_per_token_batches). When provided,
|
||||
skips the global litellm.get_model_info() lookup so that
|
||||
deployment-specific pricing is used.
|
||||
"""
|
||||
|
||||
_, custom_llm_provider, _, _ = litellm.get_llm_provider(
|
||||
|
|
@ -1911,12 +1918,13 @@ def batch_cost_calculator(
|
|||
custom_llm_provider,
|
||||
)
|
||||
|
||||
try:
|
||||
model_info: Optional[ModelInfo] = litellm.get_model_info(
|
||||
model=model, custom_llm_provider=custom_llm_provider
|
||||
)
|
||||
except Exception:
|
||||
model_info = None
|
||||
if model_info is None:
|
||||
try:
|
||||
model_info = litellm.get_model_info(
|
||||
model=model, custom_llm_provider=custom_llm_provider
|
||||
)
|
||||
except Exception:
|
||||
model_info = None
|
||||
|
||||
if not model_info:
|
||||
return 0.0, 0.0
|
||||
|
|
|
|||
|
|
@ -1051,23 +1051,15 @@ class OpenTelemetry(CustomLogger):
|
|||
# See: https://github.com/open-telemetry/opentelemetry-python/pull/4676
|
||||
# TODO: Refactor to use the proper OTEL Logs API instead of directly creating SDK LogRecords
|
||||
|
||||
from opentelemetry._logs import (
|
||||
SeverityNumber,
|
||||
get_logger,
|
||||
)
|
||||
|
||||
# MyPy evaluates both branches of try/except imports and can fail when
|
||||
# newer OTEL stubs remove/relocate symbols. Gate the typing import so
|
||||
# only the canonical location is type-checked.
|
||||
if TYPE_CHECKING:
|
||||
from opentelemetry.sdk._logs._internal import LogRecord as SdkLogRecord
|
||||
else:
|
||||
try:
|
||||
from opentelemetry.sdk._logs import (
|
||||
LogRecord as SdkLogRecord, # type: ignore[attr-defined]
|
||||
)
|
||||
except ImportError:
|
||||
from opentelemetry.sdk._logs._internal import LogRecord as SdkLogRecord
|
||||
from opentelemetry._logs import SeverityNumber, get_logger
|
||||
try:
|
||||
from opentelemetry.sdk._logs import ( # type: ignore[attr-defined] # OTEL < 1.39.0
|
||||
LogRecord as SdkLogRecord,
|
||||
)
|
||||
except ImportError:
|
||||
from opentelemetry.sdk._logs._internal import (
|
||||
LogRecord as SdkLogRecord, # type: ignore[attr-defined] # OTEL >= 1.39.0
|
||||
)
|
||||
|
||||
otel_logger = get_logger(LITELLM_LOGGER_NAME)
|
||||
|
||||
|
|
|
|||
|
|
@ -51,6 +51,7 @@ class S3Logger(CustomBatchLogger, BaseAWSLLM):
|
|||
s3_use_team_prefix: bool = False,
|
||||
s3_strip_base64_files: bool = False,
|
||||
s3_use_key_prefix: bool = False,
|
||||
s3_use_virtual_hosted_style: bool = False,
|
||||
**kwargs,
|
||||
):
|
||||
try:
|
||||
|
|
@ -78,7 +79,8 @@ class S3Logger(CustomBatchLogger, BaseAWSLLM):
|
|||
s3_path=s3_path,
|
||||
s3_use_team_prefix=s3_use_team_prefix,
|
||||
s3_strip_base64_files=s3_strip_base64_files,
|
||||
s3_use_key_prefix=s3_use_key_prefix
|
||||
s3_use_key_prefix=s3_use_key_prefix,
|
||||
s3_use_virtual_hosted_style=s3_use_virtual_hosted_style
|
||||
)
|
||||
verbose_logger.debug(f"s3 logger using endpoint url {s3_endpoint_url}")
|
||||
|
||||
|
|
@ -135,6 +137,7 @@ class S3Logger(CustomBatchLogger, BaseAWSLLM):
|
|||
s3_use_team_prefix: bool = False,
|
||||
s3_strip_base64_files: bool = False,
|
||||
s3_use_key_prefix: bool = False,
|
||||
s3_use_virtual_hosted_style: bool = False,
|
||||
):
|
||||
"""
|
||||
Initialize the s3 params for this logging callback
|
||||
|
|
@ -217,6 +220,11 @@ class S3Logger(CustomBatchLogger, BaseAWSLLM):
|
|||
or s3_strip_base64_files
|
||||
)
|
||||
|
||||
self.s3_use_virtual_hosted_style = (
|
||||
bool(litellm.s3_callback_params.get("s3_use_virtual_hosted_style", False))
|
||||
or s3_use_virtual_hosted_style
|
||||
)
|
||||
|
||||
return
|
||||
|
||||
async def async_log_success_event(self, kwargs, response_obj, start_time, end_time):
|
||||
|
|
@ -247,8 +255,14 @@ class S3Logger(CustomBatchLogger, BaseAWSLLM):
|
|||
standard_logging_payload=kwargs.get("standard_logging_object", None),
|
||||
)
|
||||
|
||||
# afile_delete and other non-model call types never produce a standard_logging_object,
|
||||
# so s3_batch_logging_element is None. Skip gracefully instead of raising ValueError.
|
||||
if s3_batch_logging_element is None:
|
||||
raise ValueError("s3_batch_logging_element is None")
|
||||
verbose_logger.debug(
|
||||
"s3 Logging - skipping event, no standard_logging_object for call_type=%s",
|
||||
kwargs.get("call_type", "unknown"),
|
||||
)
|
||||
return
|
||||
|
||||
verbose_logger.debug(
|
||||
"\ns3 Logger - Logging payload = %s", s3_batch_logging_element
|
||||
|
|
@ -302,13 +316,20 @@ class S3Logger(CustomBatchLogger, BaseAWSLLM):
|
|||
url = f"https://{self.s3_bucket_name}.s3.{self.s3_region_name}.amazonaws.com/{batch_logging_element.s3_object_key}"
|
||||
|
||||
if self.s3_endpoint_url and self.s3_bucket_name:
|
||||
url = (
|
||||
self.s3_endpoint_url
|
||||
+ "/"
|
||||
+ self.s3_bucket_name
|
||||
+ "/"
|
||||
+ batch_logging_element.s3_object_key
|
||||
)
|
||||
if self.s3_use_virtual_hosted_style:
|
||||
# Virtual-hosted-style: bucket.endpoint/key
|
||||
endpoint_host = self.s3_endpoint_url.replace("https://", "").replace("http://", "")
|
||||
protocol = "https://" if self.s3_endpoint_url.startswith("https://") else "http://"
|
||||
url = f"{protocol}{self.s3_bucket_name}.{endpoint_host}/{batch_logging_element.s3_object_key}"
|
||||
else:
|
||||
# Path-style: endpoint/bucket/key
|
||||
url = (
|
||||
self.s3_endpoint_url
|
||||
+ "/"
|
||||
+ self.s3_bucket_name
|
||||
+ "/"
|
||||
+ batch_logging_element.s3_object_key
|
||||
)
|
||||
|
||||
# Convert JSON to string
|
||||
json_string = safe_dumps(batch_logging_element.payload)
|
||||
|
|
@ -456,13 +477,20 @@ class S3Logger(CustomBatchLogger, BaseAWSLLM):
|
|||
url = f"https://{self.s3_bucket_name}.s3.{self.s3_region_name}.amazonaws.com/{batch_logging_element.s3_object_key}"
|
||||
|
||||
if self.s3_endpoint_url and self.s3_bucket_name:
|
||||
url = (
|
||||
self.s3_endpoint_url
|
||||
+ "/"
|
||||
+ self.s3_bucket_name
|
||||
+ "/"
|
||||
+ batch_logging_element.s3_object_key
|
||||
)
|
||||
if self.s3_use_virtual_hosted_style:
|
||||
# Virtual-hosted-style: bucket.endpoint/key
|
||||
endpoint_host = self.s3_endpoint_url.replace("https://", "").replace("http://", "")
|
||||
protocol = "https://" if self.s3_endpoint_url.startswith("https://") else "http://"
|
||||
url = f"{protocol}{self.s3_bucket_name}.{endpoint_host}/{batch_logging_element.s3_object_key}"
|
||||
else:
|
||||
# Path-style: endpoint/bucket/key
|
||||
url = (
|
||||
self.s3_endpoint_url
|
||||
+ "/"
|
||||
+ self.s3_bucket_name
|
||||
+ "/"
|
||||
+ batch_logging_element.s3_object_key
|
||||
)
|
||||
|
||||
# Convert JSON to string
|
||||
json_string = safe_dumps(batch_logging_element.payload)
|
||||
|
|
@ -550,13 +578,20 @@ class S3Logger(CustomBatchLogger, BaseAWSLLM):
|
|||
url = f"https://{self.s3_bucket_name}.s3.{self.s3_region_name}.amazonaws.com/{s3_object_key}"
|
||||
|
||||
if self.s3_endpoint_url and self.s3_bucket_name:
|
||||
url = (
|
||||
self.s3_endpoint_url
|
||||
+ "/"
|
||||
+ self.s3_bucket_name
|
||||
+ "/"
|
||||
+ s3_object_key
|
||||
)
|
||||
if self.s3_use_virtual_hosted_style:
|
||||
# Virtual-hosted-style: bucket.endpoint/key
|
||||
endpoint_host = self.s3_endpoint_url.replace("https://", "").replace("http://", "")
|
||||
protocol = "https://" if self.s3_endpoint_url.startswith("https://") else "http://"
|
||||
url = f"{protocol}{self.s3_bucket_name}.{endpoint_host}/{s3_object_key}"
|
||||
else:
|
||||
# Path-style: endpoint/bucket/key
|
||||
url = (
|
||||
self.s3_endpoint_url
|
||||
+ "/"
|
||||
+ self.s3_bucket_name
|
||||
+ "/"
|
||||
+ s3_object_key
|
||||
)
|
||||
|
||||
# Prepare the request for GET operation
|
||||
# For GET requests, we need x-amz-content-sha256 with hash of empty string
|
||||
|
|
@ -618,4 +653,4 @@ class S3Logger(CustomBatchLogger, BaseAWSLLM):
|
|||
verbose_logger.exception(
|
||||
f"Error retrieving object {object_key} from cold storage: {str(e)}"
|
||||
)
|
||||
return None
|
||||
return None
|
||||
|
|
@ -412,30 +412,45 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
|
||||
If a callback is in litellm._known_custom_logger_compatible_callbacks, it needs to be intialized and added to the respective dynamic_* callback list.
|
||||
"""
|
||||
# Process input callbacks
|
||||
self.dynamic_input_callbacks = self._process_dynamic_callback_list(
|
||||
self.dynamic_input_callbacks, dynamic_callbacks_type="input"
|
||||
)
|
||||
# Early exit if all callbacks are None (common case)
|
||||
if (
|
||||
self.dynamic_input_callbacks is None
|
||||
and self.dynamic_success_callbacks is None
|
||||
and self.dynamic_async_success_callbacks is None
|
||||
and self.dynamic_failure_callbacks is None
|
||||
and self.dynamic_async_failure_callbacks is None
|
||||
):
|
||||
return
|
||||
|
||||
# Process failure callbacks
|
||||
self.dynamic_failure_callbacks = self._process_dynamic_callback_list(
|
||||
self.dynamic_failure_callbacks, dynamic_callbacks_type="failure"
|
||||
)
|
||||
# Process input callbacks (standalone - no dependencies)
|
||||
if self.dynamic_input_callbacks is not None:
|
||||
self.dynamic_input_callbacks = self._process_dynamic_callback_list(
|
||||
self.dynamic_input_callbacks, dynamic_callbacks_type="input"
|
||||
)
|
||||
|
||||
# Process async failure callbacks
|
||||
self.dynamic_async_failure_callbacks = self._process_dynamic_callback_list(
|
||||
self.dynamic_async_failure_callbacks, dynamic_callbacks_type="async_failure"
|
||||
)
|
||||
# Process success BEFORE async_success (success processing adds to async_success)
|
||||
if self.dynamic_success_callbacks is not None:
|
||||
self.dynamic_success_callbacks = self._process_dynamic_callback_list(
|
||||
self.dynamic_success_callbacks, dynamic_callbacks_type="success"
|
||||
)
|
||||
|
||||
# Process success callbacks
|
||||
self.dynamic_success_callbacks = self._process_dynamic_callback_list(
|
||||
self.dynamic_success_callbacks, dynamic_callbacks_type="success"
|
||||
)
|
||||
# Process async_success AFTER success
|
||||
if self.dynamic_async_success_callbacks is not None:
|
||||
self.dynamic_async_success_callbacks = self._process_dynamic_callback_list(
|
||||
self.dynamic_async_success_callbacks, dynamic_callbacks_type="async_success"
|
||||
)
|
||||
|
||||
# Process async success callbacks
|
||||
self.dynamic_async_success_callbacks = self._process_dynamic_callback_list(
|
||||
self.dynamic_async_success_callbacks, dynamic_callbacks_type="async_success"
|
||||
)
|
||||
# Process failure BEFORE async_failure (failure processing adds to async_failure)
|
||||
if self.dynamic_failure_callbacks is not None:
|
||||
self.dynamic_failure_callbacks = self._process_dynamic_callback_list(
|
||||
self.dynamic_failure_callbacks, dynamic_callbacks_type="failure"
|
||||
)
|
||||
|
||||
# Process async_failure AFTER failure
|
||||
if self.dynamic_async_failure_callbacks is not None:
|
||||
self.dynamic_async_failure_callbacks = self._process_dynamic_callback_list(
|
||||
self.dynamic_async_failure_callbacks, dynamic_callbacks_type="async_failure"
|
||||
)
|
||||
|
||||
def _process_dynamic_callback_list(
|
||||
self,
|
||||
|
|
|
|||
|
|
@ -1282,9 +1282,13 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
output_config = optional_params.get("output_config")
|
||||
if output_config and isinstance(output_config, dict):
|
||||
effort = output_config.get("effort")
|
||||
if effort and effort not in ["high", "medium", "low"]:
|
||||
if effort and effort not in ["high", "medium", "low", "max"]:
|
||||
raise ValueError(
|
||||
f"Invalid effort value: {effort}. Must be one of: 'high', 'medium', 'low'"
|
||||
f"Invalid effort value: {effort}. Must be one of: 'high', 'medium', 'low', 'max'"
|
||||
)
|
||||
if effort == "max" and not self._is_claude_opus_4_6(model):
|
||||
raise ValueError(
|
||||
f"effort='max' is only supported by Claude Opus 4.6. Got model: {model}"
|
||||
)
|
||||
data["output_config"] = output_config
|
||||
|
||||
|
|
|
|||
|
|
@ -19,6 +19,7 @@ from litellm.types.llms.anthropic_messages.anthropic_response import (
|
|||
AnthropicMessagesResponse,
|
||||
)
|
||||
from litellm.types.utils import ModelResponse
|
||||
from litellm.utils import get_model_info
|
||||
|
||||
if TYPE_CHECKING:
|
||||
pass
|
||||
|
|
@ -63,6 +64,14 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
return
|
||||
|
||||
model = completion_kwargs.get("model")
|
||||
try:
|
||||
model_info = get_model_info(model=cast(str, model), custom_llm_provider=custom_llm_provider)
|
||||
if model_info and model_info.get("supports_reasoning") is False:
|
||||
# Model doesn't support reasoning/responses API, don't route
|
||||
return
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
if isinstance(model, str) and model and not model.startswith("responses/"):
|
||||
# Prefix model with "responses/" to route to OpenAI Responses API
|
||||
completion_kwargs["model"] = f"responses/{model}"
|
||||
|
|
|
|||
|
|
@ -239,8 +239,13 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
|
|||
merged_chunk["delta"] = {}
|
||||
|
||||
# Add usage to the held chunk
|
||||
uncached_input_tokens = chunk.usage.prompt_tokens or 0
|
||||
if hasattr(chunk.usage, "prompt_tokens_details") and chunk.usage.prompt_tokens_details:
|
||||
cached_tokens = getattr(chunk.usage.prompt_tokens_details, "cached_tokens", 0) or 0
|
||||
uncached_input_tokens -= cached_tokens
|
||||
|
||||
usage_dict: UsageDelta = {
|
||||
"input_tokens": chunk.usage.prompt_tokens or 0,
|
||||
"input_tokens": uncached_input_tokens,
|
||||
"output_tokens": chunk.usage.completion_tokens or 0,
|
||||
}
|
||||
# Add cache tokens if available (for prompt caching support)
|
||||
|
|
@ -412,6 +417,7 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
|
|||
if block_type == "tool_use":
|
||||
# Type narrowing: content_block_start is ToolUseBlock when block_type is "tool_use"
|
||||
from typing import cast
|
||||
|
||||
from litellm.types.llms.anthropic import ToolUseBlock
|
||||
|
||||
tool_block = cast(ToolUseBlock, content_block_start)
|
||||
|
|
@ -430,6 +436,7 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
|
|||
# if we get a function name since it signals a new tool call
|
||||
if block_type == "tool_use":
|
||||
from typing import cast
|
||||
|
||||
from litellm.types.llms.anthropic import ToolUseBlock
|
||||
|
||||
tool_block = cast(ToolUseBlock, content_block_start)
|
||||
|
|
|
|||
|
|
@ -1070,8 +1070,13 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
)
|
||||
# extract usage
|
||||
usage: Usage = getattr(response, "usage")
|
||||
uncached_input_tokens = usage.prompt_tokens or 0
|
||||
if hasattr(usage, "prompt_tokens_details") and usage.prompt_tokens_details:
|
||||
cached_tokens = getattr(usage.prompt_tokens_details, "cached_tokens", 0) or 0
|
||||
uncached_input_tokens -= cached_tokens
|
||||
|
||||
anthropic_usage = AnthropicUsage(
|
||||
input_tokens=usage.prompt_tokens or 0,
|
||||
input_tokens=uncached_input_tokens,
|
||||
output_tokens=usage.completion_tokens or 0,
|
||||
)
|
||||
# Add cache tokens if available (for prompt caching support)
|
||||
|
|
@ -1230,8 +1235,13 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
else:
|
||||
litellm_usage_chunk = None
|
||||
if litellm_usage_chunk is not None:
|
||||
uncached_input_tokens = litellm_usage_chunk.prompt_tokens or 0
|
||||
if hasattr(litellm_usage_chunk, "prompt_tokens_details") and litellm_usage_chunk.prompt_tokens_details:
|
||||
cached_tokens = getattr(litellm_usage_chunk.prompt_tokens_details, "cached_tokens", 0) or 0
|
||||
uncached_input_tokens -= cached_tokens
|
||||
|
||||
usage_delta = UsageDelta(
|
||||
input_tokens=litellm_usage_chunk.prompt_tokens or 0,
|
||||
input_tokens=uncached_input_tokens,
|
||||
output_tokens=litellm_usage_chunk.completion_tokens or 0,
|
||||
)
|
||||
# Add cache tokens if available (for prompt caching support)
|
||||
|
|
|
|||
|
|
@ -11,7 +11,10 @@ import httpx
|
|||
|
||||
import litellm
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.constants import RESPONSE_FORMAT_TOOL_NAME
|
||||
from litellm.constants import (
|
||||
BEDROCK_MIN_THINKING_BUDGET_TOKENS,
|
||||
RESPONSE_FORMAT_TOOL_NAME,
|
||||
)
|
||||
from litellm.litellm_core_utils.core_helpers import (
|
||||
filter_exceptions_from_params,
|
||||
filter_internal_params,
|
||||
|
|
@ -434,6 +437,25 @@ class AmazonConverseConfig(BaseConfig):
|
|||
reasoning_effort=reasoning_effort, model=model
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def _clamp_thinking_budget_tokens(optional_params: dict) -> None:
|
||||
"""
|
||||
Clamp thinking.budget_tokens to the Bedrock minimum (1024).
|
||||
|
||||
Bedrock returns a 400 error if budget_tokens < 1024.
|
||||
"""
|
||||
thinking = optional_params.get("thinking")
|
||||
if isinstance(thinking, dict):
|
||||
budget = thinking.get("budget_tokens")
|
||||
if isinstance(budget, int) and budget < BEDROCK_MIN_THINKING_BUDGET_TOKENS:
|
||||
verbose_logger.debug(
|
||||
"Bedrock requires thinking.budget_tokens >= %d, got %d. "
|
||||
"Clamping to minimum.",
|
||||
BEDROCK_MIN_THINKING_BUDGET_TOKENS,
|
||||
budget,
|
||||
)
|
||||
thinking["budget_tokens"] = BEDROCK_MIN_THINKING_BUDGET_TOKENS
|
||||
|
||||
def get_supported_openai_params(self, model: str) -> List[str]:
|
||||
from litellm.utils import supports_function_calling
|
||||
|
||||
|
|
@ -871,9 +893,14 @@ class AmazonConverseConfig(BaseConfig):
|
|||
Checks 'non_default_params' for 'thinking' and 'max_tokens'
|
||||
|
||||
if 'thinking' is enabled and 'max_tokens' is not specified, set 'max_tokens' to the thinking token budget + DEFAULT_MAX_TOKENS
|
||||
|
||||
Also clamps thinking.budget_tokens to the Bedrock minimum (1024) to
|
||||
prevent 400 errors from the Bedrock API.
|
||||
"""
|
||||
from litellm.constants import DEFAULT_MAX_TOKENS
|
||||
|
||||
self._clamp_thinking_budget_tokens(optional_params)
|
||||
|
||||
is_thinking_enabled = self.is_thinking_enabled(optional_params)
|
||||
is_max_tokens_in_request = self.is_max_tokens_in_request(non_default_params)
|
||||
if is_thinking_enabled and not is_max_tokens_in_request:
|
||||
|
|
|
|||
|
|
@ -73,10 +73,6 @@ class ChatGPTResponsesAPIConfig(OpenAIResponsesAPIConfig):
|
|||
litellm_params,
|
||||
headers,
|
||||
)
|
||||
request.pop("max_output_tokens", None)
|
||||
request.pop("max_tokens", None)
|
||||
request.pop("max_completion_tokens", None)
|
||||
request.pop("metadata", None)
|
||||
base_instructions = get_chatgpt_default_instructions()
|
||||
existing_instructions = request.get("instructions")
|
||||
if existing_instructions:
|
||||
|
|
@ -92,7 +88,22 @@ class ChatGPTResponsesAPIConfig(OpenAIResponsesAPIConfig):
|
|||
if "reasoning.encrypted_content" not in include:
|
||||
include.append("reasoning.encrypted_content")
|
||||
request["include"] = include
|
||||
return request
|
||||
|
||||
allowed_keys = {
|
||||
"model",
|
||||
"input",
|
||||
"instructions",
|
||||
"stream",
|
||||
"store",
|
||||
"include",
|
||||
"tools",
|
||||
"tool_choice",
|
||||
"reasoning",
|
||||
"previous_response_id",
|
||||
"truncation",
|
||||
}
|
||||
|
||||
return {k: v for k, v in request.items() if k in allowed_keys}
|
||||
|
||||
def transform_response_api_response(
|
||||
self,
|
||||
|
|
|
|||
|
|
@ -119,8 +119,13 @@ class AiohttpResponseStream(httpx.AsyncByteStream):
|
|||
|
||||
|
||||
class AiohttpTransport(httpx.AsyncBaseTransport):
|
||||
def __init__(self, client: Union[ClientSession, Callable[[], ClientSession]]) -> None:
|
||||
def __init__(
|
||||
self,
|
||||
client: Union[ClientSession, Callable[[], ClientSession]],
|
||||
owns_session: bool = True,
|
||||
) -> None:
|
||||
self.client = client
|
||||
self._owns_session = owns_session
|
||||
|
||||
#########################################################
|
||||
# Class variables for proxy settings
|
||||
|
|
@ -128,7 +133,7 @@ class AiohttpTransport(httpx.AsyncBaseTransport):
|
|||
self.proxy_cache: Dict[str, Optional[str]] = {}
|
||||
|
||||
async def aclose(self) -> None:
|
||||
if isinstance(self.client, ClientSession):
|
||||
if self._owns_session and isinstance(self.client, ClientSession):
|
||||
await self.client.close()
|
||||
|
||||
|
||||
|
|
@ -144,10 +149,11 @@ class LiteLLMAiohttpTransport(AiohttpTransport):
|
|||
self,
|
||||
client: Union[ClientSession, Callable[[], ClientSession]],
|
||||
ssl_verify: Optional[Union[bool, ssl.SSLContext]] = None,
|
||||
owns_session: bool = True,
|
||||
):
|
||||
self.client = client
|
||||
self._ssl_verify = ssl_verify # Store for per-request SSL override
|
||||
super().__init__(client=client)
|
||||
super().__init__(client=client, owns_session=owns_session)
|
||||
# Store the client factory for recreating sessions when needed
|
||||
if callable(client):
|
||||
self._client_factory = client
|
||||
|
|
|
|||
|
|
@ -866,6 +866,7 @@ class AsyncHTTPHandler:
|
|||
return LiteLLMAiohttpTransport(
|
||||
client=shared_session,
|
||||
ssl_verify=ssl_for_transport,
|
||||
owns_session=False,
|
||||
)
|
||||
|
||||
# Create new session only if none provided or existing one is invalid
|
||||
|
|
|
|||
|
|
@ -4,6 +4,7 @@ Dynamic configuration class generator for JSON-based providers.
|
|||
|
||||
from typing import Any, Coroutine, List, Literal, Optional, Tuple, Union, overload
|
||||
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.litellm_core_utils.prompt_templates.common_utils import (
|
||||
handle_messages_with_content_list_to_str_conversion,
|
||||
)
|
||||
|
|
@ -96,8 +97,27 @@ def create_config_class(provider: SimpleProviderConfig):
|
|||
return api_base
|
||||
|
||||
def get_supported_openai_params(self, model: str) -> list:
|
||||
"""Get supported OpenAI params from base class"""
|
||||
return super().get_supported_openai_params(model=model)
|
||||
"""Get supported OpenAI params, excluding tool-related params for models
|
||||
that don't support function calling."""
|
||||
from litellm.utils import supports_function_calling
|
||||
|
||||
supported_params = super().get_supported_openai_params(model=model)
|
||||
|
||||
_supports_fc = supports_function_calling(
|
||||
model=model, custom_llm_provider=provider.slug
|
||||
)
|
||||
|
||||
if not _supports_fc:
|
||||
tool_params = ["tools", "tool_choice", "function_call", "functions", "parallel_tool_calls"]
|
||||
for param in tool_params:
|
||||
if param in supported_params:
|
||||
supported_params.remove(param)
|
||||
verbose_logger.debug(
|
||||
f"Model {model} on provider {provider.slug} does not support "
|
||||
f"function calling — removed tool-related params from supported params."
|
||||
)
|
||||
|
||||
return supported_params
|
||||
|
||||
def map_openai_params(
|
||||
self,
|
||||
|
|
|
|||
|
|
@ -12456,6 +12456,19 @@
|
|||
"supports_tool_choice": true,
|
||||
"supports_web_search": true
|
||||
},
|
||||
"fireworks_ai/accounts/fireworks/models/kimi-k2p5": {
|
||||
"input_cost_per_token": 6e-07,
|
||||
"litellm_provider": "fireworks_ai",
|
||||
"max_input_tokens": 262144,
|
||||
"max_output_tokens": 262144,
|
||||
"max_tokens": 262144,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 3e-06,
|
||||
"source": "https://fireworks.ai/pricing",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": true,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
"fireworks_ai/accounts/fireworks/models/llama-v3p1-405b-instruct": {
|
||||
"input_cost_per_token": 3e-06,
|
||||
"litellm_provider": "fireworks_ai",
|
||||
|
|
@ -23759,7 +23772,7 @@
|
|||
"max_output_tokens": 131072,
|
||||
"max_tokens": 131072,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 1.5e-07,
|
||||
"output_cost_per_token": 1.5e-05,
|
||||
"source": "https://www.oracle.com/artificial-intelligence/generative-ai/generative-ai-service/pricing",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": false
|
||||
|
|
@ -23807,7 +23820,7 @@
|
|||
"max_output_tokens": 128000,
|
||||
"max_tokens": 128000,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 1.5e-07,
|
||||
"output_cost_per_token": 1.5e-05,
|
||||
"source": "https://www.oracle.com/artificial-intelligence/generative-ai/generative-ai-service/pricing",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": false
|
||||
|
|
|
|||
|
|
@ -149,7 +149,7 @@ if MCP_AVAILABLE:
|
|||
app=server,
|
||||
event_store=None,
|
||||
json_response=False, # enables SSE streaming
|
||||
stateless=False, # enables session state
|
||||
stateless=True,
|
||||
)
|
||||
|
||||
# Create SSE session manager
|
||||
|
|
|
|||
File diff suppressed because one or more lines are too long
|
|
@ -1,31 +1,31 @@
|
|||
1:"$Sreact.fragment"
|
||||
2:I[347257,["/litellm-asset-prefix/_next/static/chunks/d96012bcfc98706a.js","/litellm-asset-prefix/_next/static/chunks/dbca964212122d58.js"],"ClientPageRoot"]
|
||||
3:I[952683,["/litellm-asset-prefix/_next/static/chunks/26adfa4e8ffc85c7.js","/litellm-asset-prefix/_next/static/chunks/e8ed72789c2b42ff.js","/litellm-asset-prefix/_next/static/chunks/baa15cbb8a22e3d5.js","/litellm-asset-prefix/_next/static/chunks/9f5ccd929375c1d6.js","/litellm-asset-prefix/_next/static/chunks/1fe0596a309ad6cf.js","/litellm-asset-prefix/_next/static/chunks/e3bc795c751bb99a.js","/litellm-asset-prefix/_next/static/chunks/29f80447de6eef64.js","/litellm-asset-prefix/_next/static/chunks/5f9c3b92a016f382.js","/litellm-asset-prefix/_next/static/chunks/58b9eb1766fba8e0.js","/litellm-asset-prefix/_next/static/chunks/5eb6648cefff2d8a.js","/litellm-asset-prefix/_next/static/chunks/27195d3ec0cab1b4.js","/litellm-asset-prefix/_next/static/chunks/403c4d96324c23a6.js","/litellm-asset-prefix/_next/static/chunks/88c74f8b4b20d25a.js","/litellm-asset-prefix/_next/static/chunks/0a671fedee641c02.js","/litellm-asset-prefix/_next/static/chunks/134f728fa7099e3e.js","/litellm-asset-prefix/_next/static/chunks/fe750aa0bf04912c.js","/litellm-asset-prefix/_next/static/chunks/7b788dd93ad868b3.js","/litellm-asset-prefix/_next/static/chunks/d64d74932cb225a3.js","/litellm-asset-prefix/_next/static/chunks/7af309decf630af7.js","/litellm-asset-prefix/_next/static/chunks/4188d520ca4e5f2b.js","/litellm-asset-prefix/_next/static/chunks/64f1a2ef9113d86f.js","/litellm-asset-prefix/_next/static/chunks/457923c551f21385.js","/litellm-asset-prefix/_next/static/chunks/0aece5fc054ad66e.js","/litellm-asset-prefix/_next/static/chunks/c8a0095ffe8cea4a.js","/litellm-asset-prefix/_next/static/chunks/72250192fd3153b7.js","/litellm-asset-prefix/_next/static/chunks/a9ebedc318fa36dc.js","/litellm-asset-prefix/_next/static/chunks/3f369c603677cd7a.js","/litellm-asset-prefix/_next/static/chunks/66a190706fc6c35a.js","/litellm-asset-prefix/_next/static/chunks/3b30ab8eaa03bc21.js","/litellm-asset-prefix/_next/static/chunks/7e417dd24c8becd0.js","/litellm-asset-prefix/_next/static/chunks/e007904603a33bc5.js","/litellm-asset-prefix/_next/static/chunks/5d3e07ae5afa6fa6.js","/litellm-asset-prefix/_next/static/chunks/c7b74067c01ee971.js","/litellm-asset-prefix/_next/static/chunks/8992001a9a91bc67.js","/litellm-asset-prefix/_next/static/chunks/4980372eaa37b78b.js","/litellm-asset-prefix/_next/static/chunks/bdf355b41816a002.js","/litellm-asset-prefix/_next/static/chunks/799b258fbe06c072.js","/litellm-asset-prefix/_next/static/chunks/99cf9cf99df5ccfc.js","/litellm-asset-prefix/_next/static/chunks/00ff280cdb7d7ee5.js","/litellm-asset-prefix/_next/static/chunks/0a65da2cd24e2ab6.js","/litellm-asset-prefix/_next/static/chunks/23f80b1de2d3b634.js","/litellm-asset-prefix/_next/static/chunks/c637e0ee56f50900.js","/litellm-asset-prefix/_next/static/chunks/a382857dbbcea5d1.js","/litellm-asset-prefix/_next/static/chunks/8e12212d7a0aeaee.js","/litellm-asset-prefix/_next/static/chunks/1ab4ccc7c0ba9eff.js","/litellm-asset-prefix/_next/static/chunks/8354d717e34ebd6f.js","/litellm-asset-prefix/_next/static/chunks/2971c4658f1bcd7d.js","/litellm-asset-prefix/_next/static/chunks/6c4c97f1ea6e7d77.js","/litellm-asset-prefix/_next/static/chunks/a21582fe1f52b973.js","/litellm-asset-prefix/_next/static/chunks/496b84010c33cf69.js","/litellm-asset-prefix/_next/static/chunks/21ae464276343547.js","/litellm-asset-prefix/_next/static/chunks/c4452a79c69324a6.js","/litellm-asset-prefix/_next/static/chunks/a5fe06c2cefac5bc.js","/litellm-asset-prefix/_next/static/chunks/450ebd094f4fa24d.js","/litellm-asset-prefix/_next/static/chunks/6367dd1d1cf7eeef.js","/litellm-asset-prefix/_next/static/chunks/c24d3e9cf8b1b7ed.js"],"default"]
|
||||
3:I[952683,["/litellm-asset-prefix/_next/static/chunks/26adfa4e8ffc85c7.js","/litellm-asset-prefix/_next/static/chunks/e8ed72789c2b42ff.js","/litellm-asset-prefix/_next/static/chunks/9f5ccd929375c1d6.js","/litellm-asset-prefix/_next/static/chunks/e3bc795c751bb99a.js","/litellm-asset-prefix/_next/static/chunks/1fe0596a309ad6cf.js","/litellm-asset-prefix/_next/static/chunks/c93c5c533dba84d1.js","/litellm-asset-prefix/_next/static/chunks/47ed25bb99ff8a39.js","/litellm-asset-prefix/_next/static/chunks/5f9c3b92a016f382.js","/litellm-asset-prefix/_next/static/chunks/58b9eb1766fba8e0.js","/litellm-asset-prefix/_next/static/chunks/5eb6648cefff2d8a.js","/litellm-asset-prefix/_next/static/chunks/4188d520ca4e5f2b.js","/litellm-asset-prefix/_next/static/chunks/403c4d96324c23a6.js","/litellm-asset-prefix/_next/static/chunks/88c74f8b4b20d25a.js","/litellm-asset-prefix/_next/static/chunks/0a671fedee641c02.js","/litellm-asset-prefix/_next/static/chunks/134f728fa7099e3e.js","/litellm-asset-prefix/_next/static/chunks/fe750aa0bf04912c.js","/litellm-asset-prefix/_next/static/chunks/7b788dd93ad868b3.js","/litellm-asset-prefix/_next/static/chunks/81bf20526995284e.js","/litellm-asset-prefix/_next/static/chunks/d64d74932cb225a3.js","/litellm-asset-prefix/_next/static/chunks/c91982ee39ef0f77.js","/litellm-asset-prefix/_next/static/chunks/64f1a2ef9113d86f.js","/litellm-asset-prefix/_next/static/chunks/457923c551f21385.js","/litellm-asset-prefix/_next/static/chunks/82a6c2af12705c46.js","/litellm-asset-prefix/_next/static/chunks/2f04fe05bcb1c150.js","/litellm-asset-prefix/_next/static/chunks/72250192fd3153b7.js","/litellm-asset-prefix/_next/static/chunks/a9ebedc318fa36dc.js","/litellm-asset-prefix/_next/static/chunks/3f369c603677cd7a.js","/litellm-asset-prefix/_next/static/chunks/66a190706fc6c35a.js","/litellm-asset-prefix/_next/static/chunks/3b30ab8eaa03bc21.js","/litellm-asset-prefix/_next/static/chunks/99cf9cf99df5ccfc.js","/litellm-asset-prefix/_next/static/chunks/a7aecb91c09b0e9a.js","/litellm-asset-prefix/_next/static/chunks/e007904603a33bc5.js","/litellm-asset-prefix/_next/static/chunks/c7b74067c01ee971.js","/litellm-asset-prefix/_next/static/chunks/8e12212d7a0aeaee.js","/litellm-asset-prefix/_next/static/chunks/4980372eaa37b78b.js","/litellm-asset-prefix/_next/static/chunks/bf880fd979d4a2e6.js","/litellm-asset-prefix/_next/static/chunks/7ad0165018dc89ce.js","/litellm-asset-prefix/_next/static/chunks/8354d717e34ebd6f.js","/litellm-asset-prefix/_next/static/chunks/00ff280cdb7d7ee5.js","/litellm-asset-prefix/_next/static/chunks/0a65da2cd24e2ab6.js","/litellm-asset-prefix/_next/static/chunks/3d2a01213eb1cc87.js","/litellm-asset-prefix/_next/static/chunks/7e417dd24c8becd0.js","/litellm-asset-prefix/_next/static/chunks/a382857dbbcea5d1.js","/litellm-asset-prefix/_next/static/chunks/bdf355b41816a002.js","/litellm-asset-prefix/_next/static/chunks/1ab4ccc7c0ba9eff.js","/litellm-asset-prefix/_next/static/chunks/8992001a9a91bc67.js","/litellm-asset-prefix/_next/static/chunks/2971c4658f1bcd7d.js","/litellm-asset-prefix/_next/static/chunks/6c4c97f1ea6e7d77.js","/litellm-asset-prefix/_next/static/chunks/a21582fe1f52b973.js","/litellm-asset-prefix/_next/static/chunks/5d3e07ae5afa6fa6.js","/litellm-asset-prefix/_next/static/chunks/c4452a79c69324a6.js","/litellm-asset-prefix/_next/static/chunks/496b84010c33cf69.js","/litellm-asset-prefix/_next/static/chunks/511809a345b510d8.js","/litellm-asset-prefix/_next/static/chunks/450ebd094f4fa24d.js","/litellm-asset-prefix/_next/static/chunks/6367dd1d1cf7eeef.js","/litellm-asset-prefix/_next/static/chunks/69aeba649b0dc90f.js"],"default"]
|
||||
1b:I[897367,["/litellm-asset-prefix/_next/static/chunks/d96012bcfc98706a.js","/litellm-asset-prefix/_next/static/chunks/dbca964212122d58.js"],"OutletBoundary"]
|
||||
1c:"$Sreact.suspense"
|
||||
:HL["/litellm-asset-prefix/_next/static/chunks/3f3fa56b5786d58c.css","style"]
|
||||
0:{"buildId":"FNzcPugrMYo8KWdUvIcl9","rsc":["$","$1","c",{"children":[["$","$L2",null,{"Component":"$3","serverProvidedParams":{"searchParams":{},"params":{},"promises":["$@4","$@5"]}}],[["$","link","0",{"rel":"stylesheet","href":"/litellm-asset-prefix/_next/static/chunks/3f3fa56b5786d58c.css","precedence":"next"}],["$","script","script-0",{"src":"/litellm-asset-prefix/_next/static/chunks/baa15cbb8a22e3d5.js","async":true}],["$","script","script-1",{"src":"/litellm-asset-prefix/_next/static/chunks/9f5ccd929375c1d6.js","async":true}],["$","script","script-2",{"src":"/litellm-asset-prefix/_next/static/chunks/1fe0596a309ad6cf.js","async":true}],["$","script","script-3",{"src":"/litellm-asset-prefix/_next/static/chunks/e3bc795c751bb99a.js","async":true}],["$","script","script-4",{"src":"/litellm-asset-prefix/_next/static/chunks/29f80447de6eef64.js","async":true}],["$","script","script-5",{"src":"/litellm-asset-prefix/_next/static/chunks/5f9c3b92a016f382.js","async":true}],["$","script","script-6",{"src":"/litellm-asset-prefix/_next/static/chunks/58b9eb1766fba8e0.js","async":true}],["$","script","script-7",{"src":"/litellm-asset-prefix/_next/static/chunks/5eb6648cefff2d8a.js","async":true}],["$","script","script-8",{"src":"/litellm-asset-prefix/_next/static/chunks/27195d3ec0cab1b4.js","async":true}],["$","script","script-9",{"src":"/litellm-asset-prefix/_next/static/chunks/403c4d96324c23a6.js","async":true}],["$","script","script-10",{"src":"/litellm-asset-prefix/_next/static/chunks/88c74f8b4b20d25a.js","async":true}],["$","script","script-11",{"src":"/litellm-asset-prefix/_next/static/chunks/0a671fedee641c02.js","async":true}],["$","script","script-12",{"src":"/litellm-asset-prefix/_next/static/chunks/134f728fa7099e3e.js","async":true}],["$","script","script-13",{"src":"/litellm-asset-prefix/_next/static/chunks/fe750aa0bf04912c.js","async":true}],["$","script","script-14",{"src":"/litellm-asset-prefix/_next/static/chunks/7b788dd93ad868b3.js","async":true}],["$","script","script-15",{"src":"/litellm-asset-prefix/_next/static/chunks/d64d74932cb225a3.js","async":true}],["$","script","script-16",{"src":"/litellm-asset-prefix/_next/static/chunks/7af309decf630af7.js","async":true}],["$","script","script-17",{"src":"/litellm-asset-prefix/_next/static/chunks/4188d520ca4e5f2b.js","async":true}],["$","script","script-18",{"src":"/litellm-asset-prefix/_next/static/chunks/64f1a2ef9113d86f.js","async":true}],["$","script","script-19",{"src":"/litellm-asset-prefix/_next/static/chunks/457923c551f21385.js","async":true}],["$","script","script-20",{"src":"/litellm-asset-prefix/_next/static/chunks/0aece5fc054ad66e.js","async":true}],["$","script","script-21",{"src":"/litellm-asset-prefix/_next/static/chunks/c8a0095ffe8cea4a.js","async":true}],["$","script","script-22",{"src":"/litellm-asset-prefix/_next/static/chunks/72250192fd3153b7.js","async":true}],["$","script","script-23",{"src":"/litellm-asset-prefix/_next/static/chunks/a9ebedc318fa36dc.js","async":true}],["$","script","script-24",{"src":"/litellm-asset-prefix/_next/static/chunks/3f369c603677cd7a.js","async":true}],["$","script","script-25",{"src":"/litellm-asset-prefix/_next/static/chunks/66a190706fc6c35a.js","async":true}],["$","script","script-26",{"src":"/litellm-asset-prefix/_next/static/chunks/3b30ab8eaa03bc21.js","async":true}],["$","script","script-27",{"src":"/litellm-asset-prefix/_next/static/chunks/7e417dd24c8becd0.js","async":true}],["$","script","script-28",{"src":"/litellm-asset-prefix/_next/static/chunks/e007904603a33bc5.js","async":true}],["$","script","script-29",{"src":"/litellm-asset-prefix/_next/static/chunks/5d3e07ae5afa6fa6.js","async":true}],["$","script","script-30",{"src":"/litellm-asset-prefix/_next/static/chunks/c7b74067c01ee971.js","async":true}],["$","script","script-31",{"src":"/litellm-asset-prefix/_next/static/chunks/8992001a9a91bc67.js","async":true}],["$","script","script-32",{"src":"/litellm-asset-prefix/_next/static/chunks/4980372eaa37b78b.js","async":true}],["$","script","script-33",{"src":"/litellm-asset-prefix/_next/static/chunks/bdf355b41816a002.js","async":true}],"$L6","$L7","$L8","$L9","$La","$Lb","$Lc","$Ld","$Le","$Lf","$L10","$L11","$L12","$L13","$L14","$L15","$L16","$L17","$L18","$L19"],"$L1a"]}],"loading":null,"isPartial":false}
|
||||
0:{"buildId":"C_XKHLw43nx5HaPfGD7XZ","rsc":["$","$1","c",{"children":[["$","$L2",null,{"Component":"$3","serverProvidedParams":{"searchParams":{},"params":{},"promises":["$@4","$@5"]}}],[["$","link","0",{"rel":"stylesheet","href":"/litellm-asset-prefix/_next/static/chunks/3f3fa56b5786d58c.css","precedence":"next"}],["$","script","script-0",{"src":"/litellm-asset-prefix/_next/static/chunks/9f5ccd929375c1d6.js","async":true}],["$","script","script-1",{"src":"/litellm-asset-prefix/_next/static/chunks/e3bc795c751bb99a.js","async":true}],["$","script","script-2",{"src":"/litellm-asset-prefix/_next/static/chunks/1fe0596a309ad6cf.js","async":true}],["$","script","script-3",{"src":"/litellm-asset-prefix/_next/static/chunks/c93c5c533dba84d1.js","async":true}],["$","script","script-4",{"src":"/litellm-asset-prefix/_next/static/chunks/47ed25bb99ff8a39.js","async":true}],["$","script","script-5",{"src":"/litellm-asset-prefix/_next/static/chunks/5f9c3b92a016f382.js","async":true}],["$","script","script-6",{"src":"/litellm-asset-prefix/_next/static/chunks/58b9eb1766fba8e0.js","async":true}],["$","script","script-7",{"src":"/litellm-asset-prefix/_next/static/chunks/5eb6648cefff2d8a.js","async":true}],["$","script","script-8",{"src":"/litellm-asset-prefix/_next/static/chunks/4188d520ca4e5f2b.js","async":true}],["$","script","script-9",{"src":"/litellm-asset-prefix/_next/static/chunks/403c4d96324c23a6.js","async":true}],["$","script","script-10",{"src":"/litellm-asset-prefix/_next/static/chunks/88c74f8b4b20d25a.js","async":true}],["$","script","script-11",{"src":"/litellm-asset-prefix/_next/static/chunks/0a671fedee641c02.js","async":true}],["$","script","script-12",{"src":"/litellm-asset-prefix/_next/static/chunks/134f728fa7099e3e.js","async":true}],["$","script","script-13",{"src":"/litellm-asset-prefix/_next/static/chunks/fe750aa0bf04912c.js","async":true}],["$","script","script-14",{"src":"/litellm-asset-prefix/_next/static/chunks/7b788dd93ad868b3.js","async":true}],["$","script","script-15",{"src":"/litellm-asset-prefix/_next/static/chunks/81bf20526995284e.js","async":true}],["$","script","script-16",{"src":"/litellm-asset-prefix/_next/static/chunks/d64d74932cb225a3.js","async":true}],["$","script","script-17",{"src":"/litellm-asset-prefix/_next/static/chunks/c91982ee39ef0f77.js","async":true}],["$","script","script-18",{"src":"/litellm-asset-prefix/_next/static/chunks/64f1a2ef9113d86f.js","async":true}],["$","script","script-19",{"src":"/litellm-asset-prefix/_next/static/chunks/457923c551f21385.js","async":true}],["$","script","script-20",{"src":"/litellm-asset-prefix/_next/static/chunks/82a6c2af12705c46.js","async":true}],["$","script","script-21",{"src":"/litellm-asset-prefix/_next/static/chunks/2f04fe05bcb1c150.js","async":true}],["$","script","script-22",{"src":"/litellm-asset-prefix/_next/static/chunks/72250192fd3153b7.js","async":true}],["$","script","script-23",{"src":"/litellm-asset-prefix/_next/static/chunks/a9ebedc318fa36dc.js","async":true}],["$","script","script-24",{"src":"/litellm-asset-prefix/_next/static/chunks/3f369c603677cd7a.js","async":true}],["$","script","script-25",{"src":"/litellm-asset-prefix/_next/static/chunks/66a190706fc6c35a.js","async":true}],["$","script","script-26",{"src":"/litellm-asset-prefix/_next/static/chunks/3b30ab8eaa03bc21.js","async":true}],["$","script","script-27",{"src":"/litellm-asset-prefix/_next/static/chunks/99cf9cf99df5ccfc.js","async":true}],["$","script","script-28",{"src":"/litellm-asset-prefix/_next/static/chunks/a7aecb91c09b0e9a.js","async":true}],["$","script","script-29",{"src":"/litellm-asset-prefix/_next/static/chunks/e007904603a33bc5.js","async":true}],["$","script","script-30",{"src":"/litellm-asset-prefix/_next/static/chunks/c7b74067c01ee971.js","async":true}],["$","script","script-31",{"src":"/litellm-asset-prefix/_next/static/chunks/8e12212d7a0aeaee.js","async":true}],["$","script","script-32",{"src":"/litellm-asset-prefix/_next/static/chunks/4980372eaa37b78b.js","async":true}],["$","script","script-33",{"src":"/litellm-asset-prefix/_next/static/chunks/bf880fd979d4a2e6.js","async":true}],"$L6","$L7","$L8","$L9","$La","$Lb","$Lc","$Ld","$Le","$Lf","$L10","$L11","$L12","$L13","$L14","$L15","$L16","$L17","$L18","$L19"],"$L1a"]}],"loading":null,"isPartial":false}
|
||||
4:{}
|
||||
5:"$0:rsc:props:children:0:props:serverProvidedParams:params"
|
||||
6:["$","script","script-34",{"src":"/litellm-asset-prefix/_next/static/chunks/799b258fbe06c072.js","async":true}]
|
||||
7:["$","script","script-35",{"src":"/litellm-asset-prefix/_next/static/chunks/99cf9cf99df5ccfc.js","async":true}]
|
||||
6:["$","script","script-34",{"src":"/litellm-asset-prefix/_next/static/chunks/7ad0165018dc89ce.js","async":true}]
|
||||
7:["$","script","script-35",{"src":"/litellm-asset-prefix/_next/static/chunks/8354d717e34ebd6f.js","async":true}]
|
||||
8:["$","script","script-36",{"src":"/litellm-asset-prefix/_next/static/chunks/00ff280cdb7d7ee5.js","async":true}]
|
||||
9:["$","script","script-37",{"src":"/litellm-asset-prefix/_next/static/chunks/0a65da2cd24e2ab6.js","async":true}]
|
||||
a:["$","script","script-38",{"src":"/litellm-asset-prefix/_next/static/chunks/23f80b1de2d3b634.js","async":true}]
|
||||
b:["$","script","script-39",{"src":"/litellm-asset-prefix/_next/static/chunks/c637e0ee56f50900.js","async":true}]
|
||||
a:["$","script","script-38",{"src":"/litellm-asset-prefix/_next/static/chunks/3d2a01213eb1cc87.js","async":true}]
|
||||
b:["$","script","script-39",{"src":"/litellm-asset-prefix/_next/static/chunks/7e417dd24c8becd0.js","async":true}]
|
||||
c:["$","script","script-40",{"src":"/litellm-asset-prefix/_next/static/chunks/a382857dbbcea5d1.js","async":true}]
|
||||
d:["$","script","script-41",{"src":"/litellm-asset-prefix/_next/static/chunks/8e12212d7a0aeaee.js","async":true}]
|
||||
d:["$","script","script-41",{"src":"/litellm-asset-prefix/_next/static/chunks/bdf355b41816a002.js","async":true}]
|
||||
e:["$","script","script-42",{"src":"/litellm-asset-prefix/_next/static/chunks/1ab4ccc7c0ba9eff.js","async":true}]
|
||||
f:["$","script","script-43",{"src":"/litellm-asset-prefix/_next/static/chunks/8354d717e34ebd6f.js","async":true}]
|
||||
f:["$","script","script-43",{"src":"/litellm-asset-prefix/_next/static/chunks/8992001a9a91bc67.js","async":true}]
|
||||
10:["$","script","script-44",{"src":"/litellm-asset-prefix/_next/static/chunks/2971c4658f1bcd7d.js","async":true}]
|
||||
11:["$","script","script-45",{"src":"/litellm-asset-prefix/_next/static/chunks/6c4c97f1ea6e7d77.js","async":true}]
|
||||
12:["$","script","script-46",{"src":"/litellm-asset-prefix/_next/static/chunks/a21582fe1f52b973.js","async":true}]
|
||||
13:["$","script","script-47",{"src":"/litellm-asset-prefix/_next/static/chunks/496b84010c33cf69.js","async":true}]
|
||||
14:["$","script","script-48",{"src":"/litellm-asset-prefix/_next/static/chunks/21ae464276343547.js","async":true}]
|
||||
15:["$","script","script-49",{"src":"/litellm-asset-prefix/_next/static/chunks/c4452a79c69324a6.js","async":true}]
|
||||
16:["$","script","script-50",{"src":"/litellm-asset-prefix/_next/static/chunks/a5fe06c2cefac5bc.js","async":true}]
|
||||
13:["$","script","script-47",{"src":"/litellm-asset-prefix/_next/static/chunks/5d3e07ae5afa6fa6.js","async":true}]
|
||||
14:["$","script","script-48",{"src":"/litellm-asset-prefix/_next/static/chunks/c4452a79c69324a6.js","async":true}]
|
||||
15:["$","script","script-49",{"src":"/litellm-asset-prefix/_next/static/chunks/496b84010c33cf69.js","async":true}]
|
||||
16:["$","script","script-50",{"src":"/litellm-asset-prefix/_next/static/chunks/511809a345b510d8.js","async":true}]
|
||||
17:["$","script","script-51",{"src":"/litellm-asset-prefix/_next/static/chunks/450ebd094f4fa24d.js","async":true}]
|
||||
18:["$","script","script-52",{"src":"/litellm-asset-prefix/_next/static/chunks/6367dd1d1cf7eeef.js","async":true}]
|
||||
19:["$","script","script-53",{"src":"/litellm-asset-prefix/_next/static/chunks/c24d3e9cf8b1b7ed.js","async":true}]
|
||||
19:["$","script","script-53",{"src":"/litellm-asset-prefix/_next/static/chunks/69aeba649b0dc90f.js","async":true}]
|
||||
1a:["$","$L1b",null,{"children":["$","$1c",null,{"name":"Next.MetadataOutlet","children":"$@1d"}]}]
|
||||
1d:null
|
||||
|
|
|
|||
File diff suppressed because one or more lines are too long
|
|
@ -3,4 +3,4 @@
|
|||
3:I[897367,["/litellm-asset-prefix/_next/static/chunks/d96012bcfc98706a.js","/litellm-asset-prefix/_next/static/chunks/dbca964212122d58.js"],"MetadataBoundary"]
|
||||
4:"$Sreact.suspense"
|
||||
5:I[27201,["/litellm-asset-prefix/_next/static/chunks/d96012bcfc98706a.js","/litellm-asset-prefix/_next/static/chunks/dbca964212122d58.js"],"IconMark"]
|
||||
0:{"buildId":"FNzcPugrMYo8KWdUvIcl9","rsc":["$","$1","h",{"children":[null,["$","$L2",null,{"children":[["$","meta","0",{"charSet":"utf-8"}],["$","meta","1",{"name":"viewport","content":"width=device-width, initial-scale=1"}]]}],["$","div",null,{"hidden":true,"children":["$","$L3",null,{"children":["$","$4",null,{"name":"Next.Metadata","children":[["$","title","0",{"children":"LiteLLM Dashboard"}],["$","meta","1",{"name":"description","content":"LiteLLM Proxy Admin UI"}],["$","link","2",{"rel":"icon","href":"/favicon.ico?favicon.1d32c690.ico","sizes":"48x48","type":"image/x-icon"}],["$","link","3",{"rel":"icon","href":"./favicon.ico"}],["$","$L5","4",{}]]}]}]}],["$","meta",null,{"name":"next-size-adjust","content":""}]]}],"loading":null,"isPartial":false}
|
||||
0:{"buildId":"C_XKHLw43nx5HaPfGD7XZ","rsc":["$","$1","h",{"children":[null,["$","$L2",null,{"children":[["$","meta","0",{"charSet":"utf-8"}],["$","meta","1",{"name":"viewport","content":"width=device-width, initial-scale=1"}]]}],["$","div",null,{"hidden":true,"children":["$","$L3",null,{"children":["$","$4",null,{"name":"Next.Metadata","children":[["$","title","0",{"children":"LiteLLM Dashboard"}],["$","meta","1",{"name":"description","content":"LiteLLM Proxy Admin UI"}],["$","link","2",{"rel":"icon","href":"/favicon.ico?favicon.1d32c690.ico","sizes":"48x48","type":"image/x-icon"}],["$","link","3",{"rel":"icon","href":"./favicon.ico"}],["$","$L5","4",{}]]}]}]}],["$","meta",null,{"name":"next-size-adjust","content":""}]]}],"loading":null,"isPartial":false}
|
||||
|
|
|
|||
|
|
@ -4,4 +4,4 @@
|
|||
4:I[837457,["/litellm-asset-prefix/_next/static/chunks/d96012bcfc98706a.js","/litellm-asset-prefix/_next/static/chunks/dbca964212122d58.js"],"default"]
|
||||
:HL["/litellm-asset-prefix/_next/static/chunks/4e20891f2fd03463.css","style"]
|
||||
:HL["/litellm-asset-prefix/_next/static/chunks/d682c064a60ae3d6.css","style"]
|
||||
0:{"buildId":"FNzcPugrMYo8KWdUvIcl9","rsc":["$","$1","c",{"children":[[["$","link","0",{"rel":"stylesheet","href":"/litellm-asset-prefix/_next/static/chunks/4e20891f2fd03463.css","precedence":"next"}],["$","link","1",{"rel":"stylesheet","href":"/litellm-asset-prefix/_next/static/chunks/d682c064a60ae3d6.css","precedence":"next"}],["$","script","script-0",{"src":"/litellm-asset-prefix/_next/static/chunks/26adfa4e8ffc85c7.js","async":true}],["$","script","script-1",{"src":"/litellm-asset-prefix/_next/static/chunks/e8ed72789c2b42ff.js","async":true}]],["$","html",null,{"lang":"en","children":["$","body",null,{"className":"inter_5972bc34-module__OU16Qa__className","children":["$","$L2",null,{"children":["$","$L3",null,{"parallelRouterKey":"children","template":["$","$L4",null,{}],"notFound":[[["$","title",null,{"children":"404: This page could not be found."}],["$","div",null,{"style":{"fontFamily":"system-ui,\"Segoe UI\",Roboto,Helvetica,Arial,sans-serif,\"Apple Color Emoji\",\"Segoe UI Emoji\"","height":"100vh","textAlign":"center","display":"flex","flexDirection":"column","alignItems":"center","justifyContent":"center"},"children":["$","div",null,{"children":[["$","style",null,{"dangerouslySetInnerHTML":{"__html":"body{color:#000;background:#fff;margin:0}.next-error-h1{border-right:1px solid rgba(0,0,0,.3)}@media (prefers-color-scheme:dark){body{color:#fff;background:#000}.next-error-h1{border-right:1px solid rgba(255,255,255,.3)}}"}}],["$","h1",null,{"className":"next-error-h1","style":{"display":"inline-block","margin":"0 20px 0 0","padding":"0 23px 0 0","fontSize":24,"fontWeight":500,"verticalAlign":"top","lineHeight":"49px"},"children":404}],["$","div",null,{"style":{"display":"inline-block"},"children":["$","h2",null,{"style":{"fontSize":14,"fontWeight":400,"lineHeight":"49px","margin":0},"children":"This page could not be found."}]}]]}]}]],[]]}]}]}]}]]}],"loading":null,"isPartial":false}
|
||||
0:{"buildId":"C_XKHLw43nx5HaPfGD7XZ","rsc":["$","$1","c",{"children":[[["$","link","0",{"rel":"stylesheet","href":"/litellm-asset-prefix/_next/static/chunks/4e20891f2fd03463.css","precedence":"next"}],["$","link","1",{"rel":"stylesheet","href":"/litellm-asset-prefix/_next/static/chunks/d682c064a60ae3d6.css","precedence":"next"}],["$","script","script-0",{"src":"/litellm-asset-prefix/_next/static/chunks/26adfa4e8ffc85c7.js","async":true}],["$","script","script-1",{"src":"/litellm-asset-prefix/_next/static/chunks/e8ed72789c2b42ff.js","async":true}]],["$","html",null,{"lang":"en","children":["$","body",null,{"className":"inter_5972bc34-module__OU16Qa__className","children":["$","$L2",null,{"children":["$","$L3",null,{"parallelRouterKey":"children","template":["$","$L4",null,{}],"notFound":[[["$","title",null,{"children":"404: This page could not be found."}],["$","div",null,{"style":{"fontFamily":"system-ui,\"Segoe UI\",Roboto,Helvetica,Arial,sans-serif,\"Apple Color Emoji\",\"Segoe UI Emoji\"","height":"100vh","textAlign":"center","display":"flex","flexDirection":"column","alignItems":"center","justifyContent":"center"},"children":["$","div",null,{"children":[["$","style",null,{"dangerouslySetInnerHTML":{"__html":"body{color:#000;background:#fff;margin:0}.next-error-h1{border-right:1px solid rgba(0,0,0,.3)}@media (prefers-color-scheme:dark){body{color:#fff;background:#000}.next-error-h1{border-right:1px solid rgba(255,255,255,.3)}}"}}],["$","h1",null,{"className":"next-error-h1","style":{"display":"inline-block","margin":"0 20px 0 0","padding":"0 23px 0 0","fontSize":24,"fontWeight":500,"verticalAlign":"top","lineHeight":"49px"},"children":404}],["$","div",null,{"style":{"display":"inline-block"},"children":["$","h2",null,{"style":{"fontSize":14,"fontWeight":400,"lineHeight":"49px","margin":0},"children":"This page could not be found."}]}]]}]}]],[]]}]}]}]}]]}],"loading":null,"isPartial":false}
|
||||
|
|
|
|||
|
|
@ -2,4 +2,4 @@
|
|||
:HL["/litellm-asset-prefix/_next/static/chunks/d682c064a60ae3d6.css","style"]
|
||||
:HL["/litellm-asset-prefix/_next/static/media/83afe278b6a6bb3c-s.p.3a6ba036.woff2","font",{"crossOrigin":"","type":"font/woff2"}]
|
||||
:HL["/litellm-asset-prefix/_next/static/chunks/3f3fa56b5786d58c.css","style"]
|
||||
0:{"buildId":"FNzcPugrMYo8KWdUvIcl9","tree":{"name":"","paramType":null,"paramKey":"","hasRuntimePrefetch":false,"slots":{"children":{"name":"__PAGE__","paramType":null,"paramKey":"__PAGE__","hasRuntimePrefetch":false,"slots":null,"isRootLayout":false}},"isRootLayout":true},"staleTime":300}
|
||||
0:{"buildId":"C_XKHLw43nx5HaPfGD7XZ","tree":{"name":"","paramType":null,"paramKey":"","hasRuntimePrefetch":false,"slots":{"children":{"name":"__PAGE__","paramType":null,"paramKey":"__PAGE__","hasRuntimePrefetch":false,"slots":null,"isRootLayout":false}},"isRootLayout":true},"staleTime":300}
|
||||
|
|
|
|||
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue