diff --git a/.circleci/config.yml b/.circleci/config.yml
index 02a9e3b0714..e171759f1c4 100644
--- a/.circleci/config.yml
+++ b/.circleci/config.yml
@@ -112,14 +112,14 @@ jobs:
python -m mypy .
cd ..
no_output_timeout: 10m
- local_testing:
+ local_testing_part1:
docker:
- image: cimg/python:3.12
auth:
username: ${DOCKERHUB_USERNAME}
password: ${DOCKERHUB_PASSWORD}
working_directory: ~/project
-
+ parallelism: 4
steps:
- checkout
- setup_google_dns
@@ -205,20 +205,32 @@ jobs:
# Run pytest and generate JUnit XML report
- run:
- name: Run tests
+ name: Run tests (Part 1 - A-M)
command: |
- pwd
- ls
- # Add --timeout to kill hanging tests after 300s (5 min)
- # Add -v to show test names as they run for debugging
- # Add --tb=short for shorter tracebacks
- python -m pytest -vv tests/local_testing --cov=litellm --cov-report=xml --junitxml=test-results/junit.xml --durations=20 -k "not test_python_38.py and not test_basic_python_version.py and not router and not assistants and not langfuse and not caching and not cache" -n 4 --timeout=300 --timeout_method=thread
+ mkdir test-results
+
+ # Discover test files (A-M)
+ TEST_FILES=$(circleci tests glob "tests/local_testing/**/test_[a-mA-M]*.py")
+
+ echo "$TEST_FILES" | circleci tests run \
+ --split-by=timings \
+ --verbose \
+ --command="xargs python -m pytest \
+ -vv \
+ --cov=litellm \
+ --cov-report=xml \
+ --junitxml=test-results/junit.xml \
+ --durations=20 \
+ -k \"not test_python_38.py and not test_basic_python_version.py and not router and not assistants and not langfuse and not caching and not cache\" \
+ -n 4 \
+ --timeout=300 \
+ --timeout_method=thread"
no_output_timeout: 120m
- run:
name: Rename the coverage files
command: |
- mv coverage.xml local_testing_coverage.xml
- mv .coverage local_testing_coverage
+ mv coverage.xml local_testing_part1_coverage.xml
+ mv .coverage local_testing_part1_coverage
# Store test results
- store_test_results:
@@ -226,8 +238,136 @@ jobs:
- persist_to_workspace:
root: .
paths:
- - local_testing_coverage.xml
- - local_testing_coverage
+ - local_testing_part1_coverage.xml
+ - local_testing_part1_coverage
+ local_testing_part2:
+ docker:
+ - image: cimg/python:3.12
+ auth:
+ username: ${DOCKERHUB_USERNAME}
+ password: ${DOCKERHUB_PASSWORD}
+ working_directory: ~/project
+ parallelism: 4
+ steps:
+ - checkout
+ - setup_google_dns
+ - run:
+ name: Show git commit hash
+ command: |
+ echo "Git commit hash: $CIRCLE_SHA1"
+
+ - restore_cache:
+ keys:
+ - v1-dependencies-{{ checksum ".circleci/requirements.txt" }}
+ - run:
+ name: Install Dependencies
+ command: |
+ python -m pip install --upgrade pip
+ python -m pip install -r .circleci/requirements.txt
+ pip install "pytest==7.3.1"
+ pip install "pytest-retry==1.6.3"
+ pip install "pytest-asyncio==0.21.1"
+ pip install "pytest-cov==5.0.0"
+ pip install "mypy==1.18.2"
+ pip install "google-generativeai==0.3.2"
+ pip install "google-cloud-aiplatform==1.43.0"
+ pip install pyarrow
+ pip install "boto3==1.36.0"
+ pip install "aioboto3==13.4.0"
+ pip install langchain
+ pip install lunary==0.2.5
+ pip install "azure-identity==1.16.1"
+ pip install "langfuse==2.59.7"
+ pip install "logfire==0.29.0"
+ pip install numpydoc
+ pip install traceloop-sdk==0.21.1
+ pip install opentelemetry-api==1.25.0
+ pip install opentelemetry-sdk==1.25.0
+ pip install opentelemetry-exporter-otlp==1.25.0
+ pip install openai==1.100.1
+ pip install prisma==0.11.0
+ pip install "detect_secrets==1.5.0"
+ pip install "httpx==0.24.1"
+ pip install "respx==0.22.0"
+ pip install fastapi
+ pip install "gunicorn==21.2.0"
+ pip install "anyio==4.2.0"
+ pip install "aiodynamo==23.10.1"
+ pip install "asyncio==3.4.3"
+ pip install "apscheduler==3.10.4"
+ pip install "PyGithub==1.59.1"
+ pip install argon2-cffi
+ pip install "pytest-mock==3.12.0"
+ pip install python-multipart
+ pip install google-cloud-aiplatform
+ pip install prometheus-client==0.20.0
+ pip install "pydantic==2.10.2"
+ pip install "diskcache==5.6.1"
+ pip install "Pillow==10.3.0"
+ pip install "jsonschema==4.22.0"
+ pip install "pytest-xdist==3.6.1"
+ pip install "pytest-timeout==2.2.0"
+ pip install "websockets==13.1.0"
+ pip install semantic_router --no-deps
+ pip install aurelio_sdk --no-deps
+ pip uninstall posthog -y
+ - setup_litellm_enterprise_pip
+ - save_cache:
+ paths:
+ - ./venv
+ key: v1-dependencies-{{ checksum ".circleci/requirements.txt" }}
+ - run:
+ name: Run prisma ./docker/entrypoint.sh
+ command: |
+ set +e
+ chmod +x docker/entrypoint.sh
+ ./docker/entrypoint.sh
+ set -e
+ - run:
+ name: Black Formatting
+ command: |
+ cd litellm
+ python -m pip install black
+ python -m black .
+ cd ..
+
+ # Run pytest and generate JUnit XML report
+ - run:
+ name: Run tests (Part 2 - N-Z)
+ command: |
+ mkdir test-results
+
+ # Discover test files (N-Z)
+ TEST_FILES=$(circleci tests glob "tests/local_testing/**/test_[n-zN-Z]*.py")
+
+ echo "$TEST_FILES" | circleci tests run \
+ --split-by=timings \
+ --verbose \
+ --command="xargs python -m pytest \
+ -vv \
+ --cov=litellm \
+ --cov-report=xml \
+ --junitxml=test-results/junit.xml \
+ --durations=20 \
+ -k \"not test_python_38.py and not test_basic_python_version.py and not router and not assistants and not langfuse and not caching and not cache\" \
+ -n 4 \
+ --timeout=300 \
+ --timeout_method=thread"
+ no_output_timeout: 120m
+ - run:
+ name: Rename the coverage files
+ command: |
+ mv coverage.xml local_testing_part2_coverage.xml
+ mv .coverage local_testing_part2_coverage
+
+ # Store test results
+ - store_test_results:
+ path: test-results
+ - persist_to_workspace:
+ root: .
+ paths:
+ - local_testing_part2_coverage.xml
+ - local_testing_part2_coverage
langfuse_logging_unit_tests:
docker:
- image: cimg/python:3.11
@@ -499,7 +639,6 @@ jobs:
username: ${DOCKERHUB_USERNAME}
password: ${DOCKERHUB_PASSWORD}
working_directory: ~/project
-
steps:
- checkout
- setup_google_dns
@@ -513,6 +652,7 @@ jobs:
pip install "pytest-cov==5.0.0"
pip install "pytest-retry==1.6.3"
pip install "pytest-asyncio==0.21.1"
+ pip install "pytest-xdist==3.6.1"
pip install semantic_router --no-deps
pip install aurelio_sdk --no-deps
# Run pytest and generate JUnit XML report
@@ -575,8 +715,8 @@ jobs:
- run:
name: Rename the coverage files
command: |
- mv coverage.xml litellm_router_coverage.xml
- mv .coverage litellm_router_coverage
+ mv coverage.xml litellm_router_unit_coverage.xml
+ mv .coverage litellm_router_unit_coverage
# Store test results
- store_test_results:
path: test-results
@@ -584,8 +724,8 @@ jobs:
- persist_to_workspace:
root: .
paths:
- - litellm_router_coverage.xml
- - litellm_router_coverage
+ - litellm_router_unit_coverage.xml
+ - litellm_router_unit_coverage
litellm_security_tests:
machine:
image: ubuntu-2204:2023.10.1
@@ -1115,7 +1255,15 @@ jobs:
ls
# Add --timeout to kill hanging tests after 120s (2 min)
# Add --durations=20 to show 20 slowest tests for debugging
- python -m pytest -vv tests/llm_translation --cov=litellm --cov-report=xml -v --junitxml=test-results/junit.xml --durations=20 -n 4 --timeout=120 --timeout_method=thread
+ # Subdirectories with dedicated jobs (maintain this list as new jobs are added)
+ IGNORE_DIRS=(
+ "tests/llm_translation/realtime"
+ )
+ IGNORE_ARGS=""
+ for dir in "${IGNORE_DIRS[@]}"; do
+ IGNORE_ARGS="$IGNORE_ARGS --ignore=$dir"
+ done
+ python -m pytest -vv tests/llm_translation $IGNORE_ARGS --cov=litellm --cov-report=xml -v --junitxml=test-results/junit.xml --durations=20 -n 4 --timeout=120 --timeout_method=thread
no_output_timeout: 120m
- run:
name: Rename the coverage files
@@ -1131,6 +1279,54 @@ jobs:
paths:
- llm_translation_coverage.xml
- llm_translation_coverage
+ realtime_translation_testing:
+ docker:
+ - image: cimg/python:3.11
+ auth:
+ username: ${DOCKERHUB_USERNAME}
+ password: ${DOCKERHUB_PASSWORD}
+ working_directory: ~/project
+
+ steps:
+ - checkout
+ - setup_google_dns
+ - run:
+ name: Install Dependencies
+ command: |
+ python -m pip install --upgrade pip
+ python -m pip install -r requirements.txt
+ pip install "pytest==7.3.1"
+ pip install "pytest-retry==1.6.3"
+ pip install "pytest-cov==5.0.0"
+ pip install "pytest-asyncio==0.21.1"
+ pip install "respx==0.22.0"
+ pip install "pytest-xdist==3.6.1"
+ pip install "pytest-timeout==2.2.0"
+ pip install "websockets"
+ # Run pytest and generate JUnit XML report
+ - run:
+ name: Run realtime tests
+ command: |
+ pwd
+ ls
+ # Add --timeout to kill hanging tests after 120s (2 min)
+ # Add --durations=20 to show 20 slowest tests for debugging
+ python -m pytest -vv tests/llm_translation/realtime --cov=litellm --cov-report=xml -v --junitxml=test-results/junit.xml --durations=20 -n 4 --timeout=120 --timeout_method=thread
+ no_output_timeout: 120m
+ - run:
+ name: Rename the coverage files
+ command: |
+ mv coverage.xml realtime_translation_coverage.xml
+ mv .coverage realtime_translation_coverage
+
+ # Store test results
+ - store_test_results:
+ path: test-results
+ - persist_to_workspace:
+ root: .
+ paths:
+ - realtime_translation_coverage.xml
+ - realtime_translation_coverage
mcp_testing:
docker:
- image: cimg/python:3.11
@@ -1176,6 +1372,51 @@ jobs:
paths:
- mcp_coverage.xml
- mcp_coverage
+ agent_testing:
+ docker:
+ - image: cimg/python:3.11
+ auth:
+ username: ${DOCKERHUB_USERNAME}
+ password: ${DOCKERHUB_PASSWORD}
+ working_directory: ~/project
+
+ steps:
+ - checkout
+ - setup_google_dns
+ - run:
+ name: Install Dependencies
+ command: |
+ python -m pip install --upgrade pip
+ python -m pip install -r requirements.txt
+ pip install "pytest==7.3.1"
+ pip install "pytest-retry==1.6.3"
+ pip install "pytest-cov==5.0.0"
+ pip install "pytest-asyncio==0.21.1"
+ pip install "respx==0.22.0"
+ pip install "pydantic==2.11.0"
+ pip install "a2a-sdk"
+ # Run pytest and generate JUnit XML report
+ - run:
+ name: Run tests
+ command: |
+ pwd
+ ls
+ python -m pytest -vv tests/agent_tests --ignore=tests/agent_tests/local_only_agent_tests --cov=litellm --cov-report=xml -x -s -v --junitxml=test-results/junit.xml --durations=5
+ no_output_timeout: 120m
+ - run:
+ name: Rename the coverage files
+ command: |
+ mv coverage.xml agent_coverage.xml
+ mv .coverage agent_coverage
+
+ # Store test results
+ - store_test_results:
+ path: test-results
+ - persist_to_workspace:
+ root: .
+ paths:
+ - agent_coverage.xml
+ - agent_coverage
guardrails_testing:
docker:
- image: cimg/python:3.11
@@ -1743,13 +1984,14 @@ jobs:
pip install "pytest-cov==5.0.0"
pip install "pytest-asyncio==0.21.1"
pip install "respx==0.22.0"
+ pip install "pytest-xdist==3.6.1"
# Run pytest and generate JUnit XML report
- run:
name: Run tests
command: |
pwd
ls
- python -m pytest -vv tests/image_gen_tests --cov=litellm --cov-report=xml -x -v --junitxml=test-results/junit.xml --durations=5
+ python -m pytest -vv tests/image_gen_tests -n 4 --cov=litellm --cov-report=xml -x -v --junitxml=test-results/junit.xml --durations=5
no_output_timeout: 120m
- run:
name: Rename the coverage files
@@ -1792,6 +2034,7 @@ jobs:
pip install "mlflow==2.17.2"
pip install "anthropic==0.52.0"
pip install "blockbuster==1.5.24"
+ pip install "pytest-xdist==3.6.1"
# Run pytest and generate JUnit XML report
- setup_litellm_enterprise_pip
- run:
@@ -1799,7 +2042,7 @@ jobs:
command: |
pwd
ls
- python -m pytest -vv tests/logging_callback_tests --cov=litellm --cov-report=xml -s -v --junitxml=test-results/junit.xml --durations=5
+ python -m pytest -vv tests/logging_callback_tests --cov=litellm -n 4 --cov-report=xml -s -v --junitxml=test-results/junit.xml --durations=5
no_output_timeout: 120m
- run:
name: Rename the coverage files
@@ -2192,6 +2435,8 @@ jobs:
pip install "asyncio==3.4.3"
pip install "PyGithub==1.59.1"
pip install "openai==1.100.1"
+ pip install "litellm[proxy]"
+ pip install "pytest-xdist==3.6.1"
- run:
name: Install dockerize
command: |
@@ -2268,7 +2513,7 @@ jobs:
command: |
pwd
ls
- python -m pytest -s -vv tests/*.py -x --junitxml=test-results/junit.xml --durations=5 --ignore=tests/otel_tests --ignore=tests/spend_tracking_tests --ignore=tests/pass_through_tests --ignore=tests/proxy_admin_ui_tests --ignore=tests/load_tests --ignore=tests/llm_translation --ignore=tests/llm_responses_api_testing --ignore=tests/mcp_tests --ignore=tests/guardrails_tests --ignore=tests/image_gen_tests --ignore=tests/pass_through_unit_tests
+ python -m pytest -s -vv tests/*.py -x --junitxml=test-results/junit.xml -n 4 --durations=5 --ignore=tests/otel_tests --ignore=tests/spend_tracking_tests --ignore=tests/pass_through_tests --ignore=tests/proxy_admin_ui_tests --ignore=tests/load_tests --ignore=tests/llm_translation --ignore=tests/llm_responses_api_testing --ignore=tests/mcp_tests --ignore=tests/guardrails_tests --ignore=tests/image_gen_tests --ignore=tests/pass_through_unit_tests
no_output_timeout: 120m
# Store test results
@@ -3263,6 +3508,110 @@ jobs:
- store_test_results:
path: test-results
+ proxy_e2e_anthropic_messages_tests:
+ machine:
+ image: ubuntu-2204:2023.10.1
+ resource_class: xlarge
+ working_directory: ~/project
+ steps:
+ - checkout
+ - setup_google_dns
+ - run:
+ name: Install Docker CLI (In case it's not already installed)
+ command: |
+ curl -fsSL https://get.docker.com | sh
+ sudo usermod -aG docker $USER
+ docker version
+ - run:
+ name: Install Python 3.10
+ command: |
+ curl https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh --output miniconda.sh
+ bash miniconda.sh -b -p $HOME/miniconda
+ export PATH="$HOME/miniconda/bin:$PATH"
+ conda init bash
+ source ~/.bashrc
+ conda create -n myenv python=3.10 -y
+ conda activate myenv
+ python --version
+ - run:
+ name: Install Dependencies
+ command: |
+ export PATH="$HOME/miniconda/bin:$PATH"
+ source $HOME/miniconda/etc/profile.d/conda.sh
+ conda activate myenv
+ pip install "pytest==7.3.1"
+ pip install "pytest-asyncio==0.21.1"
+ pip install "boto3==1.36.0"
+ pip install "httpx==0.27.0"
+ pip install "claude-agent-sdk"
+ pip install -r requirements.txt
+ - run:
+ name: Install dockerize
+ command: |
+ wget https://github.com/jwilder/dockerize/releases/download/v0.6.1/dockerize-linux-amd64-v0.6.1.tar.gz
+ sudo tar -C /usr/local/bin -xzvf dockerize-linux-amd64-v0.6.1.tar.gz
+ rm dockerize-linux-amd64-v0.6.1.tar.gz
+ - run:
+ name: Start PostgreSQL Database
+ command: |
+ docker run -d \
+ --name postgres-db \
+ -e POSTGRES_USER=postgres \
+ -e POSTGRES_PASSWORD=postgres \
+ -e POSTGRES_DB=circle_test \
+ -p 5432:5432 \
+ postgres:14
+ - run:
+ name: Wait for PostgreSQL to be ready
+ command: dockerize -wait tcp://localhost:5432 -timeout 1m
+ - attach_workspace:
+ at: ~/project
+ - run:
+ name: Load Docker Database Image
+ command: |
+ gunzip -c litellm-docker-database.tar.gz | docker load
+ docker images | grep litellm-docker-database
+ - run:
+ name: Run Docker container with test config
+ command: |
+ docker run -d \
+ -p 4000:4000 \
+ -e DATABASE_URL=postgresql://postgres:postgres@host.docker.internal:5432/circle_test \
+ -e LITELLM_MASTER_KEY="sk-1234" \
+ -e AWS_ACCESS_KEY_ID=$AWS_ACCESS_KEY_ID \
+ -e AWS_SECRET_ACCESS_KEY=$AWS_SECRET_ACCESS_KEY \
+ -e AWS_REGION_NAME="us-east-1" \
+ --add-host host.docker.internal:host-gateway \
+ --name my-app \
+ -v $(pwd)/tests/proxy_e2e_anthropic_messages_tests/test_config.yaml:/app/config.yaml \
+ litellm-docker-database:ci \
+ --config /app/config.yaml \
+ --port 4000 \
+ --detailed_debug
+ - run:
+ name: Start outputting logs
+ command: docker logs -f my-app
+ background: true
+ - run:
+ name: Wait for app to be ready
+ command: dockerize -wait http://localhost:4000 -timeout 5m
+ - run:
+ name: Run Claude Agent SDK E2E Tests
+ command: |
+ export PATH="$HOME/miniconda/bin:$PATH"
+ source $HOME/miniconda/etc/profile.d/conda.sh
+ conda activate myenv
+ export LITELLM_PROXY_URL="http://localhost:4000"
+ export LITELLM_API_KEY="sk-1234"
+ pwd
+ ls
+ python -m pytest -vv tests/proxy_e2e_anthropic_messages_tests/ -x -s --junitxml=test-results/junit.xml --durations=5
+ no_output_timeout: 120m
+
+ # Store test results
+ - store_test_results:
+ path: test-results
+
upload-coverage:
docker:
- image: cimg/python:3.9
@@ -3284,7 +3633,7 @@ jobs:
python -m venv venv
. venv/bin/activate
pip install coverage
- coverage combine llm_translation_coverage llm_responses_api_coverage ocr_coverage search_coverage mcp_coverage logging_coverage audio_coverage litellm_router_coverage local_testing_coverage litellm_assistants_api_coverage auth_ui_unit_tests_coverage langfuse_coverage caching_coverage litellm_proxy_unit_tests_part1_coverage litellm_proxy_unit_tests_part2_coverage image_gen_coverage pass_through_unit_tests_coverage batches_coverage litellm_security_tests_coverage guardrails_coverage litellm_mapped_tests_coverage
+ coverage combine llm_translation_coverage realtime_translation_coverage llm_responses_api_coverage ocr_coverage search_coverage mcp_coverage logging_coverage audio_coverage litellm_router_coverage litellm_router_unit_coverage local_testing_part1_coverage local_testing_part2_coverage litellm_assistants_api_coverage auth_ui_unit_tests_coverage langfuse_coverage caching_coverage litellm_proxy_unit_tests_part1_coverage litellm_proxy_unit_tests_part2_coverage image_gen_coverage pass_through_unit_tests_coverage batches_coverage litellm_security_tests_coverage guardrails_coverage litellm_mapped_tests_coverage
coverage xml
- codecov/upload:
file: ./coverage.xml
@@ -3334,8 +3683,22 @@ jobs:
ls dist/
twine upload --verbose dist/*
else
- echo "Version ${VERSION} of package is already published on PyPI. Skipping PyPI publish."
- circleci step halt
+ echo "Version ${VERSION} of package is already published on PyPI."
+
+ # Check if corresponding Docker nightly image exists
+ NIGHTLY_TAG="v${VERSION}-nightly"
+ echo "Checking for Docker nightly image: litellm/litellm:${NIGHTLY_TAG}"
+
+ # Check Docker Hub for the nightly image
+ if curl -s "https://hub.docker.com/v2/repositories/litellm/litellm/tags/${NIGHTLY_TAG}" | grep -q "name"; then
+ echo "Docker nightly image ${NIGHTLY_TAG} exists. This release was already completed successfully."
+ echo "Skipping PyPI publish and continuing to ensure Docker images are up to date."
+ circleci step halt
+ else
+ echo "ERROR: PyPI package ${VERSION} exists but Docker nightly image ${NIGHTLY_TAG} does not exist!"
+ echo "This indicates an incomplete release. Please investigate."
+ exit 1
+ fi
fi
- run:
name: Trigger Github Action for new Docker Container + Trigger Load Testing
@@ -3344,11 +3707,21 @@ jobs:
python3 -m pip install toml
VERSION=$(python3 -c "import toml; print(toml.load('pyproject.toml')['tool']['poetry']['version'])")
echo "LiteLLM Version ${VERSION}"
+
+ # Determine which branch to use for Docker build
+ if [[ "$CIRCLE_BRANCH" =~ ^litellm_release_day_.* ]]; then
+ BUILD_BRANCH="$CIRCLE_BRANCH"
+ echo "Using release branch: $BUILD_BRANCH"
+ else
+ BUILD_BRANCH="main"
+ echo "Using default branch: $BUILD_BRANCH"
+ fi
+
curl -X POST \
-H "Accept: application/vnd.github.v3+json" \
-H "Authorization: Bearer $GITHUB_TOKEN" \
"https://api.github.com/repos/BerriAI/litellm/actions/workflows/ghcr_deploy.yml/dispatches" \
- -d "{\"ref\":\"main\", \"inputs\":{\"tag\":\"v${VERSION}-nightly\", \"commit_hash\":\"$CIRCLE_SHA1\"}}"
+ -d "{\"ref\":\"${BUILD_BRANCH}\", \"inputs\":{\"tag\":\"v${VERSION}-nightly\", \"commit_hash\":\"$CIRCLE_SHA1\"}}"
echo "triggering load testing server for version ${VERSION} and commit ${CIRCLE_SHA1}"
curl -X POST "https://proxyloadtester-production.up.railway.app/start/load/test?version=${VERSION}&commit_hash=${CIRCLE_SHA1}&release_type=nightly"
@@ -3482,6 +3855,9 @@ jobs:
cd ui/litellm-dashboard
+ # Remove node_modules and package-lock to ensure clean install (fixes dependency resolution issues)
+ rm -rf node_modules package-lock.json
+
# Install dependencies first
npm install
@@ -3739,7 +4115,13 @@ workflows:
only:
- main
- /litellm_.*/
- - local_testing:
+ - local_testing_part1:
+ filters:
+ branches:
+ only:
+ - main
+ - /litellm_.*/
+ - local_testing_part2:
filters:
branches:
only:
@@ -3901,18 +4283,38 @@ workflows:
only:
- main
- /litellm_.*/
+ - proxy_e2e_anthropic_messages_tests:
+ requires:
+ - build_docker_database_image
+ filters:
+ branches:
+ only:
+ - main
+ - /litellm_.*/
- llm_translation_testing:
filters:
branches:
only:
- main
- /litellm_.*/
+ - realtime_translation_testing:
+ filters:
+ branches:
+ only:
+ - main
+ - /litellm_.*/
- mcp_testing:
filters:
branches:
only:
- main
- /litellm_.*/
+ - agent_testing:
+ filters:
+ branches:
+ only:
+ - main
+ - /litellm_.*/
- guardrails_testing:
filters:
branches:
@@ -4018,7 +4420,9 @@ workflows:
- upload-coverage:
requires:
- llm_translation_testing
+ - realtime_translation_testing
- mcp_testing
+ - agent_testing
- google_generate_content_endpoint_testing
- guardrails_testing
- llm_responses_api_testing
@@ -4044,7 +4448,8 @@ workflows:
- litellm_proxy_unit_testing_part2
- litellm_security_tests
- langfuse_logging_unit_tests
- - local_testing
+ - local_testing_part1
+ - local_testing_part2
- litellm_assistants_api_testing
- auth_ui_unit_tests
- db_migration_disable_update_check:
@@ -4084,15 +4489,19 @@ workflows:
branches:
only:
- main
+ - /litellm_release_day_.*/
- publish_to_pypi:
requires:
- mypy_linting
- - local_testing
+ - local_testing_part1
+ - local_testing_part2
- build_and_test
- e2e_openai_endpoints
- test_bad_database_url
- llm_translation_testing
+ - realtime_translation_testing
- mcp_testing
+ - agent_testing
- google_generate_content_endpoint_testing
- llm_responses_api_testing
- ocr_testing
diff --git a/.circleci/requirements.txt b/.circleci/requirements.txt
index 8c44dc18305..a5ec74424fe 100644
--- a/.circleci/requirements.txt
+++ b/.circleci/requirements.txt
@@ -16,4 +16,5 @@ uvloop==0.21.0
mcp==1.25.0 # for MCP server
semantic_router==0.1.10 # for auto-routing with litellm
fastuuid==0.12.0
-responses==0.25.7 # for proxy client tests
\ No newline at end of file
+responses==0.25.7 # for proxy client tests
+pytest-retry==1.6.3 # for automatic test retries
\ No newline at end of file
diff --git a/.github/workflows/create_daily_staging_branch.yml b/.github/workflows/create_daily_staging_branch.yml
index a97cf6f9740..9d0093e8b16 100644
--- a/.github/workflows/create_daily_staging_branch.yml
+++ b/.github/workflows/create_daily_staging_branch.yml
@@ -2,7 +2,7 @@ name: Create Daily Staging Branch
on:
schedule:
- - cron: '0 0 * * *' # Runs daily at midnight UTC
+ - cron: '0 0,12 * * *' # Runs every 12 hours at midnight and noon UTC
workflow_dispatch: # Allow manual trigger
jobs:
@@ -24,7 +24,7 @@ jobs:
git config user.email "github-actions[bot]@users.noreply.github.com"
# Generate branch name with MM_DD_YYYY format
- BRANCH_NAME="litellm_staging_$(date +'%m_%d_%Y')"
+ BRANCH_NAME="litellm_oss_staging_$(date +'%m_%d_%Y')"
echo "Creating branch: $BRANCH_NAME"
# Fetch all branches
diff --git a/.github/workflows/test-linting.yml b/.github/workflows/test-linting.yml
index 35ebffeada3..7c5c269f899 100644
--- a/.github/workflows/test-linting.yml
+++ b/.github/workflows/test-linting.yml
@@ -73,4 +73,4 @@ jobs:
- name: Check import safety
run: |
- poetry run python -c "from litellm import *" || (echo '🚨 import failed, this means you introduced unprotected imports! 🚨'; exit 1)
\ No newline at end of file
+ poetry run python -c "from litellm import *" || (echo '🚨 import failed, this means you introduced unprotected imports! 🚨'; exit 1)
diff --git a/.github/workflows/test-litellm.yml b/.github/workflows/test-litellm.yml
index ba32dc1bf54..d9cf2e74a11 100644
--- a/.github/workflows/test-litellm.yml
+++ b/.github/workflows/test-litellm.yml
@@ -34,7 +34,7 @@ jobs:
poetry run pip install "google-genai==1.22.0"
poetry run pip install "google-cloud-aiplatform>=1.38"
poetry run pip install "fastapi-offline==1.7.3"
- poetry run pip install "python-multipart==0.0.18"
+ poetry run pip install "python-multipart==0.0.22"
poetry run pip install "openapi-core"
- name: Setup litellm-enterprise as local package
run: |
diff --git a/.github/workflows/test-model-map.yaml b/.github/workflows/test-model-map.yaml
new file mode 100644
index 00000000000..ae5ac402e23
--- /dev/null
+++ b/.github/workflows/test-model-map.yaml
@@ -0,0 +1,15 @@
+name: Validate model_prices_and_context_window.json
+
+on:
+ pull_request:
+ branches: [ main ]
+
+jobs:
+ validate-model-prices-json:
+ runs-on: ubuntu-latest
+ steps:
+ - uses: actions/checkout@v4
+
+ - name: Validate model_prices_and_context_window.json
+ run: |
+ jq empty model_prices_and_context_window.json
diff --git a/.gitignore b/.gitignore
index 9d9e28dc466..ddf5f6279b3 100644
--- a/.gitignore
+++ b/.gitignore
@@ -1,5 +1,6 @@
.python-version
.venv
+.venv_policy_test
.env
.newenv
newenv/*
@@ -59,10 +60,6 @@ litellm/proxy/_super_secret_config.yaml
litellm/proxy/myenv/bin/activate
litellm/proxy/myenv/bin/Activate.ps1
myenv/*
-litellm/proxy/_experimental/out/_next/
-litellm/proxy/_experimental/out/404/index.html
-litellm/proxy/_experimental/out/model_hub/index.html
-litellm/proxy/_experimental/out/onboarding/index.html
litellm/tests/log.txt
litellm/tests/langfuse.log
litellm/tests/langfuse.log
@@ -75,9 +72,6 @@ tests/local_testing/log.txt
litellm/proxy/_new_new_secret_config.yaml
litellm/proxy/custom_guardrail.py
.mypy_cache/*
-litellm/proxy/_experimental/out/404.html
-litellm/proxy/_experimental/out/404.html
-litellm/proxy/_experimental/out/model_hub.html
.mypy_cache/*
litellm/proxy/application.log
tests/llm_translation/vertex_test_account.json
@@ -99,9 +93,9 @@ litellm_config.yaml
litellm/proxy/to_delete_loadtest_work/*
update_model_cost_map.py
tests/test_litellm/proxy/_experimental/mcp_server/test_mcp_server_manager.py
-litellm/proxy/_experimental/out/guardrails/index.html
scripts/test_vertex_ai_search.py
LAZY_LOADING_IMPROVEMENTS.md
+STABILIZATION_TODO.md
**/test-results
**/playwright-report
**/*.storageState.json
diff --git a/.trivyignore b/.trivyignore
new file mode 100644
index 00000000000..0d04ecacdb5
--- /dev/null
+++ b/.trivyignore
@@ -0,0 +1,12 @@
+# LiteLLM Trivy Ignore File
+# CVEs listed here are temporarily allowlisted pending fixes
+
+# Next.js vulnerabilities in UI dashboard (next@14.2.35)
+# Allowlisted: 2026-01-31, 7-day fix timeline
+# Fix: Upgrade to Next.js 15.5.10+ or 16.1.5+
+
+# HIGH: DoS via request deserialization
+GHSA-h25m-26qc-wcjf
+
+# MEDIUM: Image Optimizer DoS
+CVE-2025-59471
diff --git a/AGENTS.md b/AGENTS.md
index 61afbd035fe..5a48049ef45 100644
--- a/AGENTS.md
+++ b/AGENTS.md
@@ -51,12 +51,14 @@ LiteLLM is a unified interface for 100+ LLMs that:
### MAKING CODE CHANGES FOR THE UI (IGNORE FOR BACKEND)
-1. **Use Common Components as much as possible**:
+1. **Tremor is DEPRECATED, do not use Tremor components in new features/changes**
+ - The only exception is the Tremor Table component and its required Tremor Table sub components.
+
+2. **Use Common Components as much as possible**:
- These are usually defined in the `common_components` directory
- Use these components as much as possible and avoid building new components unless needed
- - Tremor components are deprecated; prefer using Ant Design (AntD) as much as possible
-2. **Testing**:
+3. **Testing**:
- The codebase uses **Vitest** and **React Testing Library**
- **Query Priority Order**: Use query methods in this order: `getByRole`, `getByLabelText`, `getByPlaceholderText`, `getByText`, `getByTestId`
- **Always use `screen`** instead of destructuring from `render()` (e.g., use `screen.getByText()` not `getByText`)
diff --git a/CLAUDE.md b/CLAUDE.md
index 23a0e97eaee..3cb67908076 100644
--- a/CLAUDE.md
+++ b/CLAUDE.md
@@ -90,6 +90,7 @@ LiteLLM is a unified interface for 100+ LLM providers with two main components:
- Pydantic v2 for data validation
- Async/await patterns throughout
- Type hints required for all public APIs
+- **Avoid imports within methods** — place all imports at the top of the file (module-level). Inline imports inside functions/methods make dependencies harder to trace and hurt readability. The only exception is avoiding circular imports where absolutely necessary.
### Testing Strategy
- Unit tests in `tests/test_litellm/`
diff --git a/Dockerfile b/Dockerfile
index 0e7a8412bbc..4bfda939110 100644
--- a/Dockerfile
+++ b/Dockerfile
@@ -46,8 +46,9 @@ FROM $LITELLM_RUNTIME_IMAGE AS runtime
# Ensure runtime stage runs as root
USER root
-# Install runtime dependencies
-RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip
+# Install runtime dependencies (libsndfile needed for audio processing on ARM64)
+RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip libsndfile && \
+ npm install -g npm@latest tar@latest
WORKDIR /app
# Copy the current directory contents into the container at /app
@@ -69,8 +70,8 @@ RUN find /usr/lib -type f -path "*/tornado/test/*" -delete && \
# Convert Windows line endings to Unix and make executable
RUN sed -i 's/\r$//' docker/install_auto_router.sh && chmod +x docker/install_auto_router.sh && ./docker/install_auto_router.sh
-# Generate prisma client
-RUN prisma generate
+# Generate prisma client using the correct schema
+RUN prisma generate --schema=./litellm/proxy/schema.prisma
# Convert Windows line endings to Unix for entrypoint scripts
RUN sed -i 's/\r$//' docker/entrypoint.sh && chmod +x docker/entrypoint.sh
RUN sed -i 's/\r$//' docker/prod_entrypoint.sh && chmod +x docker/prod_entrypoint.sh
diff --git a/Makefile b/Makefile
index 0da83c363cd..b867d7ea35e 100644
--- a/Makefile
+++ b/Makefile
@@ -1,7 +1,10 @@
# LiteLLM Makefile
# Simple Makefile for running tests and basic development tasks
-.PHONY: help test test-unit test-integration test-unit-helm lint format install-dev install-proxy-dev install-test-deps install-helm-unittest check-circular-imports check-import-safety
+.PHONY: help test test-unit test-integration test-unit-helm \
+ info lint lint-dev format \
+ install-dev install-proxy-dev install-test-deps \
+ install-helm-unittest check-circular-imports check-import-safety
# Default target
help:
@@ -25,6 +28,13 @@ help:
@echo " make test-integration - Run integration tests"
@echo " make test-unit-helm - Run helm unit tests"
+# Keep PIP simple for edge cases:
+PIP := $(shell command -v pip > /dev/null 2>&1 && echo "pip" || echo "python3 -m pip")
+
+# Show info
+info:
+ @echo "PIP: $(PIP)"
+
# Installation targets
install-dev:
poetry install --with dev
@@ -34,19 +44,19 @@ install-proxy-dev:
# CI-compatible installations (matches GitHub workflows exactly)
install-dev-ci:
- pip install openai==2.8.0
+ $(PIP) install openai==2.8.0
poetry install --with dev
- pip install openai==2.8.0
+ $(PIP) install openai==2.8.0
install-proxy-dev-ci:
poetry install --with dev,proxy-dev --extras proxy
- pip install openai==2.8.0
+ $(PIP) install openai==2.8.0
install-test-deps: install-proxy-dev
- poetry run pip install "pytest-retry==1.6.3"
- poetry run pip install pytest-xdist
- poetry run pip install openapi-core
- cd enterprise && poetry run pip install -e . && cd ..
+ poetry run $(PIP) install "pytest-retry==1.6.3"
+ poetry run $(PIP) install pytest-xdist
+ poetry run $(PIP) install openapi-core
+ cd enterprise && poetry run $(PIP) install -e . && cd ..
install-helm-unittest:
helm plugin install https://github.com/helm-unittest/helm-unittest --version v0.4.4 || echo "ignore error if plugin exists"
@@ -62,8 +72,40 @@ format-check: install-dev
lint-ruff: install-dev
cd litellm && poetry run ruff check . && cd ..
+# faster linter for developing ...
+# inspiration from:
+# https://github.com/astral-sh/ruff/discussions/10977
+# https://github.com/astral-sh/ruff/discussions/4049
+lint-format-changed: install-dev
+ @git diff origin/main --unified=0 --no-color -- '*.py' | \
+ perl -ne '\
+ if (/^diff --git a\/(.*) b\//) { $$file = $$1; } \
+ if (/^@@ .* \+(\d+)(?:,(\d+))? @@/) { \
+ $$start = $$1; $$count = $$2 || 1; $$end = $$start + $$count - 1; \
+ print "$$file:$$start:1-$$end:999\n"; \
+ }' | \
+ while read range; do \
+ file="$${range%%:*}"; \
+ lines="$${range#*:}"; \
+ echo "Formatting $$file (lines $$lines)"; \
+ poetry run ruff format --range "$$lines" "$$file"; \
+ done
+
+lint-ruff-dev: install-dev
+ @tmpfile=$$(mktemp /tmp/ruff-dev.XXXXXX) && \
+ cd litellm && \
+ (poetry run ruff check . --output-format=pylint || true) > "$$tmpfile" && \
+ poetry run diff-quality --violations=pylint "$$tmpfile" --compare-branch=origin/main && \
+ cd .. ; \
+ rm -f "$$tmpfile"
+
+lint-ruff-FULL-dev: install-dev
+ @files=$$(git diff --name-only origin/main -- '*.py'); \
+ if [ -n "$$files" ]; then echo "$$files" | xargs poetry run ruff check; \
+ else echo "No changed .py files to check."; fi
+
lint-mypy: install-dev
- poetry run pip install types-requests types-setuptools types-redis types-PyYAML
+ poetry run $(PIP) install types-requests types-setuptools types-redis types-PyYAML
cd litellm && poetry run mypy . --ignore-missing-imports && cd ..
lint-black: format-check
@@ -72,11 +114,14 @@ check-circular-imports: install-dev
cd litellm && poetry run python ../tests/documentation_tests/test_circular_imports.py && cd ..
check-import-safety: install-dev
- poetry run python -c "from litellm import *" || (echo '🚨 import failed, this means you introduced unprotected imports! 🚨'; exit 1)
+ @poetry run python -c "from litellm import *; print('[from litellm import *] OK! no issues!');" || (echo '🚨 import failed, this means you introduced unprotected imports! 🚨'; exit 1)
# Combined linting (matches test-linting.yml workflow)
lint: format-check lint-ruff lint-mypy check-circular-imports check-import-safety
+# Faster linting for local development (only checks changed code)
+lint-dev: lint-format-changed lint-mypy check-circular-imports check-import-safety
+
# Testing targets
test:
poetry run pytest tests/
diff --git a/README.md b/README.md
index 58ffa12c5e1..77adddf8978 100644
--- a/README.md
+++ b/README.md
@@ -258,6 +258,19 @@ LiteLLM Performance: **8ms P95 latency** at 1k RPS (See benchmarks [here](https:
Support for more providers. Missing a provider or LLM Platform, raise a [feature request](https://github.com/BerriAI/litellm/issues/new?assignees=&labels=enhancement&projects=&template=feature_request.yml&title=%5BFeature%5D%3A+).
+## OSS Adopters
+
+
+
+
+
+
+
+
Netflix
+
+
+
+
## Supported Providers ([Website Supported Models](https://models.litellm.ai/) | [Docs](https://docs.litellm.ai/docs/providers))
| Provider | `/chat/completions` | `/messages` | `/responses` | `/embeddings` | `/image/generations` | `/audio/transcriptions` | `/audio/speech` | `/moderations` | `/batches` | `/rerank` |
diff --git a/ci_cd/security_scans.sh b/ci_cd/security_scans.sh
index 04f3e27a944..340f8e96063 100755
--- a/ci_cd/security_scans.sh
+++ b/ci_cd/security_scans.sh
@@ -81,10 +81,10 @@ run_trivy_scans() {
echo "Running Trivy scans..."
echo "Scanning LiteLLM Docs..."
- trivy fs --scanners vuln --dependency-tree --exit-code 1 --severity HIGH,CRITICAL,MEDIUM ./docs/
+ trivy fs --ignorefile .trivyignore --scanners vuln --dependency-tree --exit-code 1 --severity HIGH,CRITICAL,MEDIUM ./docs/
echo "Scanning LiteLLM UI..."
- trivy fs --scanners vuln --dependency-tree --exit-code 1 --severity HIGH,CRITICAL,MEDIUM ./ui/
+ trivy fs --ignorefile .trivyignore --scanners vuln --dependency-tree --exit-code 1 --severity HIGH,CRITICAL,MEDIUM ./ui/
echo "Trivy scans completed successfully"
}
@@ -137,7 +137,24 @@ run_grype_scans() {
"CVE-2019-1010025" # glibc pthread heap address leak - awaiting patched Wolfi glibc build
"CVE-2026-22184" # zlib untgz buffer overflow - untgz unused + no fixed Wolfi build yet
"GHSA-58pv-8j8x-9vj2" # jaraco.context path traversal - setuptools vendored only (v5.3.0), not used in application code (using v6.1.0+)
+ "GHSA-34x7-hfp2-rc4v" # node-tar hardlink path traversal - not applicable, tar CLI not exposed in application code
"GHSA-r6q2-hw4h-h46w" # node-tar not used by application runtime, Linux-only container, not affect by macOS APFS-specific exploit
+ "GHSA-8rrh-rw8j-w5fx" # wheel is from chainguard and will be handled by then TODO: Remove this after Chainguard updates the wheel
+ "CVE-2025-59465" # We do not use Node in application runtime, only used for building Admin UI
+ "CVE-2025-55131" # We do not use Node in application runtime, only used for building Admin UI
+ "CVE-2025-59466" # We do not use Node in application runtime, only used for building Admin UI
+ "CVE-2025-55130" # We do not use Node in application runtime, only used for building Admin UI
+ "CVE-2025-59467" # We do not use Node in application runtime, only used for building Admin UI
+ "CVE-2026-21637" # We do not use Node in application runtime, only used for building Admin UI
+ "CVE-2025-15281" # No fix available yet
+ "CVE-2026-0865" # No fix available yet
+ "CVE-2025-15282" # No fix available yet
+ "CVE-2026-0672" # No fix available yet
+ "CVE-2025-15366" # No fix available yet
+ "CVE-2025-15367" # No fix available yet
+ "CVE-2025-12781" # No fix available yet
+ "CVE-2025-11468" # No fix available yet
+ "CVE-2026-1299" # Python 3.13 email module header injection - not applicable, LiteLLM doesn't use BytesGenerator for email serialization
)
# Build JSON array of allowlisted CVE IDs for jq
diff --git a/cookbook/anthropic_agent_sdk/README.md b/cookbook/anthropic_agent_sdk/README.md
new file mode 100644
index 00000000000..294d949e24e
--- /dev/null
+++ b/cookbook/anthropic_agent_sdk/README.md
@@ -0,0 +1,144 @@
+# Claude Agent SDK with LiteLLM Gateway
+
+A simple example showing how to use Claude's Agent SDK with LiteLLM as a proxy. This lets you use any LLM provider (OpenAI, Bedrock, Azure, etc.) through the Agent SDK.
+
+## Quick Start
+
+### 1. Install dependencies
+
+```bash
+pip install anthropic claude-agent-sdk litellm
+```
+
+### 2. Start LiteLLM proxy
+
+```bash
+# Simple start with Claude
+litellm --model claude-sonnet-4-20250514
+
+# Or with a config file
+litellm --config config.yaml
+```
+
+### 3. Run the chat
+
+**Basic Agent (no MCP):**
+
+```bash
+python main.py
+```
+
+**Agent with MCP (DeepWiki2 for research):**
+
+```bash
+python agent_with_mcp.py
+```
+
+If MCP connection fails, you can disable it:
+
+```bash
+USE_MCP=false python agent_with_mcp.py
+```
+
+That's it! You can now chat with the agent in your terminal.
+
+### Chat Commands
+
+While chatting, you can use these commands:
+- `models` - List all available models (fetched from your LiteLLM proxy)
+- `model` - Switch to a different model
+- `clear` - Start a new conversation
+- `quit` or `exit` - End the chat
+
+The chat automatically fetches available models from your LiteLLM proxy's `/models` endpoint, so you'll always see what's currently configured.
+
+## Configuration
+
+Set these environment variables if needed:
+
+```bash
+export LITELLM_PROXY_URL="http://localhost:4000"
+export LITELLM_API_KEY="sk-1234"
+export LITELLM_MODEL="bedrock-claude-sonnet-4.5"
+```
+
+Or just use the defaults - it'll connect to `http://localhost:4000` by default.
+
+## Files
+
+- `main.py` - Basic interactive agent without MCP
+- `agent_with_mcp.py` - Agent with MCP server integration (DeepWiki2)
+- `common.py` - Shared utilities and functions
+- `config.example.yaml` - Example LiteLLM configuration
+- `requirements.txt` - Python dependencies
+
+## Example Config File
+
+If you want to use multiple models, create a `config.yaml` (see `config.example.yaml`):
+
+```yaml
+model_list:
+ - model_name: bedrock-claude-sonnet-4
+ litellm_params:
+ model: "bedrock/us.anthropic.claude-sonnet-4-20250514-v1:0"
+ aws_region_name: "us-east-1"
+
+ - model_name: bedrock-claude-sonnet-4.5
+ litellm_params:
+ model: "bedrock/us.anthropic.claude-sonnet-4-5-20250929-v1:0"
+ aws_region_name: "us-east-1"
+```
+
+Then start LiteLLM with: `litellm --config config.yaml`
+
+## How It Works
+
+The key is pointing the Agent SDK to LiteLLM instead of directly to Anthropic:
+
+```python
+# Point to LiteLLM gateway (not Anthropic)
+os.environ["ANTHROPIC_BASE_URL"] = "http://localhost:4000"
+os.environ["ANTHROPIC_API_KEY"] = "sk-1234" # Your LiteLLM key
+
+# Use any model configured in LiteLLM
+options = ClaudeAgentOptions(
+ model="bedrock-claude-sonnet-4", # or gpt-4, or anything else
+ system_prompt="You are a helpful assistant.",
+ max_turns=50,
+)
+```
+
+Note: Don't add `/anthropic` to the base URL - LiteLLM handles the routing automatically.
+
+## Why Use This?
+
+- **Switch providers easily**: Use the same code with OpenAI, Bedrock, Azure, etc.
+- **Cost tracking**: LiteLLM tracks spending across all your agent conversations
+- **Rate limiting**: Set budgets and limits on your agent usage
+- **Load balancing**: Distribute requests across multiple API keys or regions
+- **Fallbacks**: Automatically retry with a different model if one fails
+
+## Troubleshooting
+
+**Connection errors?**
+- Make sure LiteLLM is running: `litellm --model your-model`
+- Check the URL is correct (default: `http://localhost:4000`)
+
+**Authentication errors?**
+- Verify your LiteLLM API key is correct
+- Make sure the model is configured in your LiteLLM setup
+
+**Model not found?**
+- Check the model name matches what's in your LiteLLM config
+- Run `litellm --model your-model` to test it works
+
+**Agent with MCP stuck or failing?**
+- The MCP server might not be available at `http://localhost:4000/mcp/deepwiki2`
+- Try disabling MCP: `USE_MCP=false python agent_with_mcp.py`
+- Or use the basic agent: `python main.py`
+
+## Learn More
+
+- [LiteLLM Docs](https://docs.litellm.ai/)
+- [Claude Agent SDK](https://github.com/anthropics/anthropic-agent-sdk)
+- [LiteLLM Proxy Guide](https://docs.litellm.ai/docs/proxy/quick_start)
diff --git a/cookbook/anthropic_agent_sdk/agent_with_mcp.py b/cookbook/anthropic_agent_sdk/agent_with_mcp.py
new file mode 100644
index 00000000000..ff25feb777f
--- /dev/null
+++ b/cookbook/anthropic_agent_sdk/agent_with_mcp.py
@@ -0,0 +1,140 @@
+"""
+Interactive Claude Agent SDK CLI with MCP Support
+
+This example demonstrates an interactive CLI chat with the Anthropic Agent SDK using LiteLLM as a proxy,
+with MCP (Model Context Protocol) server integration for enhanced capabilities.
+"""
+
+import asyncio
+import os
+from claude_agent_sdk import ClaudeSDKClient, ClaudeAgentOptions
+from common import (
+ Config,
+ fetch_available_models,
+ setup_litellm_env,
+ print_header,
+ handle_model_list,
+ handle_model_switch,
+ stream_response,
+)
+
+
+async def interactive_chat_with_mcp():
+ """
+ Interactive CLI chat with the agent and MCP server
+ """
+ config = Config()
+
+ # Configure Anthropic SDK to point to LiteLLM gateway
+ litellm_base_url = setup_litellm_env(config)
+
+ # Fetch available models from proxy
+ available_models = await fetch_available_models(litellm_base_url, config.LITELLM_API_KEY)
+
+ current_model = config.LITELLM_MODEL
+
+ # MCP server configuration
+ mcp_server_url = f"{litellm_base_url}/mcp/deepwiki2"
+ use_mcp = os.getenv("USE_MCP", "true").lower() == "true"
+
+ if not use_mcp:
+ print("⚠️ MCP disabled via USE_MCP=false")
+
+ print_header(litellm_base_url, current_model, has_mcp=use_mcp)
+
+ while True:
+ # Configure agent options
+ if use_mcp:
+ try:
+ # Try with MCP server (HTTP transport)
+ # Using McpHttpServerConfig format from Agent SDK
+ options = ClaudeAgentOptions(
+ system_prompt="You are a helpful AI assistant with access to DeepWiki for research. Be concise, accurate, and friendly.",
+ model=current_model,
+ max_turns=50,
+ mcp_servers={
+ "deepwiki2": {
+ "type": "http",
+ "url": mcp_server_url,
+ "headers": {
+ "Authorization": f"Bearer {config.LITELLM_API_KEY}"
+ }
+ }
+ },
+ )
+ except Exception as e:
+ print(f"⚠️ Warning: Could not configure MCP server: {e}")
+ print("Continuing without MCP...\n")
+ use_mcp = False
+ options = ClaudeAgentOptions(
+ system_prompt="You are a helpful AI assistant. Be concise, accurate, and friendly.",
+ model=current_model,
+ max_turns=50,
+ )
+ else:
+ # Without MCP
+ options = ClaudeAgentOptions(
+ system_prompt="You are a helpful AI assistant. Be concise, accurate, and friendly.",
+ model=current_model,
+ max_turns=50,
+ )
+
+ # Create agent client
+ try:
+ async with ClaudeSDKClient(options=options) as client:
+ conversation_active = True
+
+ while conversation_active:
+ # Get user input
+ try:
+ user_input = input("\n👤 You: ").strip()
+ except (EOFError, KeyboardInterrupt):
+ print("\n\n👋 Goodbye!")
+ return
+
+ # Handle commands
+ if user_input.lower() in ['quit', 'exit']:
+ print("\n👋 Goodbye!")
+ return
+
+ if user_input.lower() == 'clear':
+ print("\n🔄 Starting new conversation...\n")
+ conversation_active = False
+ continue
+
+ if user_input.lower() == 'models':
+ handle_model_list(available_models, current_model)
+ continue
+
+ if user_input.lower() == 'model':
+ new_model, should_restart = handle_model_switch(available_models, current_model)
+ if should_restart:
+ current_model = new_model
+ conversation_active = False
+ continue
+
+ if not user_input:
+ continue
+
+ # Stream response from agent
+ await stream_response(client, user_input)
+
+ except Exception as e:
+ print(f"\n❌ Error creating agent client: {e}")
+ print("This might be an MCP configuration issue. Try running without MCP:")
+ print(" USE_MCP=false python agent_with_mcp.py")
+ print("\nOr use the basic agent:")
+ print(" python main.py")
+ return
+
+
+def main():
+ """Run interactive chat with MCP"""
+ try:
+ asyncio.run(interactive_chat_with_mcp())
+ except KeyboardInterrupt:
+ print("\n\n👋 Goodbye!")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/cookbook/anthropic_agent_sdk/common.py b/cookbook/anthropic_agent_sdk/common.py
new file mode 100644
index 00000000000..d9ee65cb58d
--- /dev/null
+++ b/cookbook/anthropic_agent_sdk/common.py
@@ -0,0 +1,160 @@
+"""
+Common utilities for Claude Agent SDK examples
+"""
+
+import os
+import httpx
+
+
+class Config:
+ """Configuration for LiteLLM Gateway connection"""
+
+ # LiteLLM proxy URL (default to local instance)
+ LITELLM_PROXY_URL = os.getenv("LITELLM_PROXY_URL", "http://localhost:4000")
+
+ # LiteLLM API key (master key or virtual key)
+ LITELLM_API_KEY = os.getenv("LITELLM_API_KEY", "sk-1234")
+
+ # Model name as configured in LiteLLM (e.g., "bedrock-claude-sonnet-4", "gpt-4", etc.)
+ LITELLM_MODEL = os.getenv("LITELLM_MODEL", "bedrock-claude-sonnet-4.5")
+
+
+async def fetch_available_models(base_url: str, api_key: str) -> list[str]:
+ """
+ Fetch available models from LiteLLM proxy /models endpoint
+ """
+ try:
+ async with httpx.AsyncClient() as client:
+ response = await client.get(
+ f"{base_url}/models",
+ headers={"Authorization": f"Bearer {api_key}"},
+ timeout=10.0
+ )
+ response.raise_for_status()
+ data = response.json()
+ return [model["id"] for model in data.get("data", [])]
+ except Exception as e:
+ print(f"⚠️ Warning: Could not fetch models from proxy: {e}")
+ print("Using default model list...")
+ # Fallback to default models
+ return [
+ "bedrock-claude-sonnet-3.5",
+ "bedrock-claude-sonnet-4",
+ "bedrock-claude-sonnet-4.5",
+ "bedrock-claude-opus-4.5",
+ "bedrock-nova-premier",
+ ]
+
+
+def setup_litellm_env(config: Config):
+ """
+ Configure environment variables to point Agent SDK to LiteLLM
+ """
+ litellm_base_url = config.LITELLM_PROXY_URL.rstrip('/')
+ os.environ["ANTHROPIC_BASE_URL"] = litellm_base_url
+ os.environ["ANTHROPIC_API_KEY"] = config.LITELLM_API_KEY
+ return litellm_base_url
+
+
+def print_header(base_url: str, current_model: str, has_mcp: bool = False):
+ """
+ Print the chat header
+ """
+ mcp_indicator = " + MCP" if has_mcp else ""
+ print("=" * 70)
+ print(f"🤖 Claude Agent SDK with LiteLLM Gateway{mcp_indicator} - Interactive Chat")
+ print("=" * 70)
+ print(f"🚀 Connected to: {base_url}")
+ print(f"📦 Current model: {current_model}")
+ if has_mcp:
+ print("🔌 MCP: deepwiki2 enabled")
+ print("\nType your messages below. Commands:")
+ print(" - 'quit' or 'exit' to end the conversation")
+ print(" - 'clear' to start a new conversation")
+ print(" - 'model' to switch models")
+ print(" - 'models' to list available models")
+ print("=" * 70)
+ print()
+
+
+def handle_model_list(available_models: list[str], current_model: str):
+ """
+ Display available models
+ """
+ print("\n📋 Available models:")
+ for i, model in enumerate(available_models, 1):
+ marker = "✓" if model == current_model else " "
+ print(f" {marker} {i}. {model}")
+
+
+def handle_model_switch(available_models: list[str], current_model: str) -> tuple[str, bool]:
+ """
+ Handle model switching
+
+ Returns:
+ tuple: (new_model, should_restart_conversation)
+ """
+ print("\n📋 Select a model:")
+ for i, model in enumerate(available_models, 1):
+ marker = "✓" if model == current_model else " "
+ print(f" {marker} {i}. {model}")
+
+ try:
+ choice = input("\nEnter number (or press Enter to cancel): ").strip()
+ if choice:
+ idx = int(choice) - 1
+ if 0 <= idx < len(available_models):
+ new_model = available_models[idx]
+ print(f"\n✅ Switched to: {new_model}")
+ print("🔄 Starting new conversation with new model...\n")
+ return new_model, True
+ else:
+ print("❌ Invalid choice")
+ except (ValueError, IndexError):
+ print("❌ Invalid input")
+
+ return current_model, False
+
+
+async def stream_response(client, user_input: str):
+ """
+ Stream response from the agent
+ """
+ print("\n🤖 Assistant: ", end='', flush=True)
+
+ try:
+ await client.query(user_input)
+
+ # Show loading indicator
+ print("⏳ thinking...", end='', flush=True)
+
+ # Stream the response
+ first_chunk = True
+ async for msg in client.receive_response():
+ # Clear loading indicator on first message
+ if first_chunk:
+ print("\r🤖 Assistant: ", end='', flush=True)
+ first_chunk = False
+
+ # Handle different message types
+ if hasattr(msg, 'type'):
+ if msg.type == 'content_block_delta':
+ # Streaming text delta
+ if hasattr(msg, 'delta') and hasattr(msg.delta, 'text'):
+ print(msg.delta.text, end='', flush=True)
+ elif msg.type == 'content_block_start':
+ # Start of content block
+ if hasattr(msg, 'content_block') and hasattr(msg.content_block, 'text'):
+ print(msg.content_block.text, end='', flush=True)
+
+ # Fallback to original content handling
+ if hasattr(msg, 'content'):
+ for content_block in msg.content:
+ if hasattr(content_block, 'text'):
+ print(content_block.text, end='', flush=True)
+
+ print() # New line after response
+
+ except Exception as e:
+ print(f"\r\n❌ Error: {e}")
+ print("Please check your LiteLLM gateway is running and configured correctly.")
diff --git a/cookbook/anthropic_agent_sdk/config.example.yaml b/cookbook/anthropic_agent_sdk/config.example.yaml
new file mode 100644
index 00000000000..eb1984fc4ea
--- /dev/null
+++ b/cookbook/anthropic_agent_sdk/config.example.yaml
@@ -0,0 +1,25 @@
+model_list:
+ - model_name: bedrock-claude-sonnet-3.5
+ litellm_params:
+ model: "bedrock/us.anthropic.claude-3-5-sonnet-20240620-v1:0"
+ aws_region_name: "us-east-1"
+
+ - model_name: bedrock-claude-sonnet-4
+ litellm_params:
+ model: "bedrock/us.anthropic.claude-sonnet-4-20250514-v1:0"
+ aws_region_name: "us-east-1"
+
+ - model_name: bedrock-claude-sonnet-4.5
+ litellm_params:
+ model: "bedrock/us.anthropic.claude-sonnet-4-5-20250929-v1:0"
+ aws_region_name: "us-east-1"
+
+ - model_name: bedrock-claude-opus-4.5
+ litellm_params:
+ model: "bedrock/us.anthropic.claude-opus-4-5-20251101-v1:0"
+ aws_region_name: "us-east-1"
+
+ - model_name: bedrock-nova-premier
+ litellm_params:
+ model: "bedrock/amazon.nova-premier-v1:0"
+ aws_region_name: "us-east-1"
diff --git a/cookbook/anthropic_agent_sdk/main.py b/cookbook/anthropic_agent_sdk/main.py
new file mode 100644
index 00000000000..231b57ca97b
--- /dev/null
+++ b/cookbook/anthropic_agent_sdk/main.py
@@ -0,0 +1,95 @@
+"""
+Simple Interactive Claude Agent SDK CLI using LiteLLM Gateway
+
+This example demonstrates an interactive CLI chat with the Anthropic Agent SDK using LiteLLM as a proxy.
+LiteLLM acts as a unified interface, allowing you to use any LLM provider (OpenAI, Azure, Bedrock, etc.)
+through the Claude Agent SDK by pointing it to the LiteLLM gateway.
+"""
+
+import asyncio
+from claude_agent_sdk import ClaudeSDKClient, ClaudeAgentOptions
+from common import (
+ Config,
+ fetch_available_models,
+ setup_litellm_env,
+ print_header,
+ handle_model_list,
+ handle_model_switch,
+ stream_response,
+)
+
+
+async def interactive_chat():
+ """
+ Interactive CLI chat with the agent
+ """
+ config = Config()
+
+ # Configure Anthropic SDK to point to LiteLLM gateway
+ litellm_base_url = setup_litellm_env(config)
+
+ # Fetch available models from proxy
+ available_models = await fetch_available_models(litellm_base_url, config.LITELLM_API_KEY)
+
+ current_model = config.LITELLM_MODEL
+
+ print_header(litellm_base_url, current_model)
+
+ while True:
+ # Configure agent options for each conversation
+ options = ClaudeAgentOptions(
+ system_prompt="You are a helpful AI assistant. Be concise, accurate, and friendly.",
+ model=current_model,
+ max_turns=50,
+ )
+
+ # Create agent client
+ async with ClaudeSDKClient(options=options) as client:
+ conversation_active = True
+
+ while conversation_active:
+ # Get user input
+ try:
+ user_input = input("\n👤 You: ").strip()
+ except (EOFError, KeyboardInterrupt):
+ print("\n\n👋 Goodbye!")
+ return
+
+ # Handle commands
+ if user_input.lower() in ['quit', 'exit']:
+ print("\n👋 Goodbye!")
+ return
+
+ if user_input.lower() == 'clear':
+ print("\n🔄 Starting new conversation...\n")
+ conversation_active = False
+ continue
+
+ if user_input.lower() == 'models':
+ handle_model_list(available_models, current_model)
+ continue
+
+ if user_input.lower() == 'model':
+ new_model, should_restart = handle_model_switch(available_models, current_model)
+ if should_restart:
+ current_model = new_model
+ conversation_active = False
+ continue
+
+ if not user_input:
+ continue
+
+ # Stream response from agent
+ await stream_response(client, user_input)
+
+
+def main():
+ """Run interactive chat"""
+ try:
+ asyncio.run(interactive_chat())
+ except KeyboardInterrupt:
+ print("\n\n👋 Goodbye!")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/cookbook/anthropic_agent_sdk/requirements.txt b/cookbook/anthropic_agent_sdk/requirements.txt
new file mode 100644
index 00000000000..1e810bb7d99
--- /dev/null
+++ b/cookbook/anthropic_agent_sdk/requirements.txt
@@ -0,0 +1,2 @@
+claude-agent-sdk
+httpx>=0.27.0
diff --git a/cookbook/livekit_agent_sdk/README.md b/cookbook/livekit_agent_sdk/README.md
new file mode 100644
index 00000000000..1c3f0bf9564
--- /dev/null
+++ b/cookbook/livekit_agent_sdk/README.md
@@ -0,0 +1,114 @@
+# LiveKit Voice Agent with LiteLLM Gateway
+
+Simple example showing how to use LiveKit's xAI realtime plugin with LiteLLM as a proxy. This lets you switch between xAI, OpenAI, and Azure realtime APIs without changing your code.
+
+## Quick Start
+
+### 1. Install dependencies
+
+```bash
+pip install livekit-agents[xai] websockets
+```
+
+### 2. Start LiteLLM proxy
+
+```bash
+# With xAI
+export XAI_API_KEY="your-xai-key"
+litellm --config config.yaml --port 4000
+```
+
+### 3. Run the voice agent
+
+```bash
+python main.py
+```
+
+Type your message and get a voice response from Grok!
+
+## Configuration
+
+Set these environment variables if needed:
+
+```bash
+export LITELLM_PROXY_URL="http://localhost:4000"
+export LITELLM_API_KEY="sk-1234"
+export LITELLM_MODEL="grok-voice-agent"
+```
+
+Or use the defaults - connects to `http://localhost:4000` by default.
+
+## Example Config File
+
+Create a `config.yaml` with your realtime models:
+
+```yaml
+model_list:
+ - model_name: grok-voice-agent
+ litellm_params:
+ model: xai/grok-2-vision-1212
+ api_key: os.environ/XAI_API_KEY
+ model_info:
+ mode: realtime
+
+ - model_name: openai-voice-agent
+ litellm_params:
+ model: gpt-4o-realtime-preview
+ api_key: os.environ/OPENAI_API_KEY
+ model_info:
+ mode: realtime
+
+general_settings:
+ master_key: sk-1234
+```
+
+Then start: `litellm --config config.yaml --port 4000`
+
+## How It Works
+
+LiveKit's xAI plugin connects through LiteLLM proxy by setting `base_url`:
+
+```python
+from livekit.plugins import xai
+
+model = xai.realtime.RealtimeModel(
+ voice="ara",
+ api_key="sk-1234", # LiteLLM proxy key
+ base_url="http://localhost:4000", # Point to LiteLLM
+)
+```
+
+## Switching Providers
+
+Just change the model in your config - no code changes needed:
+
+**xAI Grok:**
+```yaml
+model: xai/grok-2-vision-1212
+```
+
+**OpenAI:**
+```yaml
+model: gpt-4o-realtime-preview
+```
+
+**Azure OpenAI:**
+```yaml
+model: azure/gpt-4o-realtime-preview
+api_base: https://your-endpoint.openai.azure.com/
+```
+
+## Why Use LiteLLM?
+
+- ✅ **Switch providers** without changing agent code
+- ✅ **Cost tracking** across all voice sessions
+- ✅ **Rate limiting** and budgets
+- ✅ **Load balancing** across multiple API keys
+- ✅ **Fallbacks** to backup models
+
+## Learn More
+
+- [LiveKit xAI Realtime Tutorial](/docs/tutorials/livekit_xai_realtime)
+- [xAI Realtime Docs](/docs/providers/xai_realtime)
+- [LiveKit Agents Documentation](https://docs.livekit.io/agents/)
+- [LiteLLM Realtime API](/docs/realtime)
diff --git a/cookbook/livekit_agent_sdk/config.example.yaml b/cookbook/livekit_agent_sdk/config.example.yaml
new file mode 100644
index 00000000000..1361f36af34
--- /dev/null
+++ b/cookbook/livekit_agent_sdk/config.example.yaml
@@ -0,0 +1,21 @@
+model_list:
+ - model_name: grok-voice-agent
+ litellm_params:
+ model: xai/grok-2-vision-1212
+ api_key: os.environ/XAI_API_KEY
+ model_info:
+ mode: realtime
+
+ - model_name: openai-voice-agent
+ litellm_params:
+ model: gpt-4o-realtime-preview
+ api_key: os.environ/OPENAI_API_KEY
+ model_info:
+ mode: realtime
+
+litellm_settings:
+ drop_params: True
+ telemetry: False
+
+general_settings:
+ master_key: sk-1234 # Change this to a secure key
diff --git a/cookbook/livekit_agent_sdk/main.py b/cookbook/livekit_agent_sdk/main.py
new file mode 100644
index 00000000000..0e2d7ebdfaf
--- /dev/null
+++ b/cookbook/livekit_agent_sdk/main.py
@@ -0,0 +1,112 @@
+"""
+Simple xAI Voice Agent using LiveKit SDK with LiteLLM Gateway
+
+This example shows how to use LiveKit's xAI realtime plugin through LiteLLM proxy.
+LiteLLM acts as a unified interface, allowing you to switch between xAI, OpenAI,
+and Azure realtime APIs without changing your agent code.
+"""
+import asyncio
+import json
+import os
+import websockets
+
+# Configuration
+PROXY_URL = os.getenv("LITELLM_PROXY_URL", "http://localhost:4000")
+API_KEY = os.getenv("LITELLM_API_KEY", "sk-1234")
+MODEL = os.getenv("LITELLM_MODEL", "grok-voice-agent")
+
+
+async def run_voice_agent():
+ """
+ Simple voice agent that:
+ 1. Connects to xAI realtime API through LiteLLM proxy
+ 2. Sends a user message
+ 3. Streams back the response
+ """
+
+ url = f"ws://{PROXY_URL.replace('http://', '').replace('https://', '')}/v1/realtime?model={MODEL}"
+ headers = {"Authorization": f"Bearer {API_KEY}"}
+
+ print(f"🎙️ Connecting to voice agent...")
+ print(f" Model: {MODEL}")
+ print(f" Proxy: {PROXY_URL}")
+ print()
+
+ async with websockets.connect(url, additional_headers=headers) as ws:
+ # Receive initial connection event
+ initial = json.loads(await ws.recv())
+ print(f"✅ Connected! Event: {initial['type']}\n")
+
+ # Get user input
+ user_message = input("💬 Your message: ").strip()
+ if not user_message:
+ user_message = "Tell me a fun fact about AI!"
+
+ print(f"\n🤖 Sending to {MODEL}...\n")
+
+ # Send user message
+ await ws.send(json.dumps({
+ "type": "conversation.item.create",
+ "item": {
+ "type": "message",
+ "role": "user",
+ "content": [{"type": "input_text", "text": user_message}]
+ }
+ }))
+
+ # Request response
+ await ws.send(json.dumps({
+ "type": "response.create",
+ "response": {"modalities": ["text", "audio"]}
+ }))
+
+ # Stream response
+ print("🎤 Response: ", end='', flush=True)
+ transcript = []
+
+ try:
+ while True:
+ msg = await asyncio.wait_for(ws.recv(), timeout=15.0)
+ event = json.loads(msg)
+
+ # Capture transcript deltas
+ if event['type'] == 'response.output_audio_transcript.delta':
+ delta = event.get('delta', '')
+ if delta:
+ print(delta, end='', flush=True)
+ transcript.append(delta)
+
+ # Done when response completes
+ elif event['type'] == 'response.done':
+ break
+
+ except asyncio.TimeoutError:
+ pass
+
+ print("\n")
+
+ if transcript:
+ print(f"✅ Complete response: {''.join(transcript)}")
+
+ await ws.close()
+
+
+def main():
+ """Run the voice agent"""
+ print("=" * 70)
+ print("LiveKit xAI Voice Agent via LiteLLM Proxy")
+ print("=" * 70)
+ print()
+
+ try:
+ asyncio.run(run_voice_agent())
+ except KeyboardInterrupt:
+ print("\n\n👋 Goodbye!")
+ except Exception as e:
+ print(f"\n❌ Error: {e}")
+ print("\nMake sure LiteLLM proxy is running:")
+ print(f" litellm --config config.yaml --port 4000")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/cookbook/livekit_agent_sdk/requirements.txt b/cookbook/livekit_agent_sdk/requirements.txt
new file mode 100644
index 00000000000..9e3542fac27
--- /dev/null
+++ b/cookbook/livekit_agent_sdk/requirements.txt
@@ -0,0 +1,2 @@
+livekit-agents[xai]>=1.3.12
+websockets>=15.0.1
diff --git a/cookbook/nova_sonic_realtime.py b/cookbook/nova_sonic_realtime.py
new file mode 100644
index 00000000000..0ea0badfb01
--- /dev/null
+++ b/cookbook/nova_sonic_realtime.py
@@ -0,0 +1,284 @@
+"""
+Client script to test Nova Sonic realtime API through LiteLLM proxy.
+
+This script connects to LiteLLM proxy's realtime endpoint and enables
+speech-to-speech conversation with Bedrock Nova Sonic.
+
+Prerequisites:
+- LiteLLM proxy running with Bedrock configured
+- pyaudio installed: pip install pyaudio
+- websockets installed: pip install websockets
+
+Usage:
+ python nova_sonic_realtime.py
+"""
+
+import asyncio
+import base64
+import json
+import pyaudio
+import websockets
+from typing import Optional
+
+# Audio configuration (matching Nova Sonic requirements)
+INPUT_SAMPLE_RATE = 16000 # Nova Sonic expects 16kHz input
+OUTPUT_SAMPLE_RATE = 24000 # Nova Sonic outputs 24kHz
+CHANNELS = 1
+FORMAT = pyaudio.paInt16
+CHUNK_SIZE = 1024
+
+# LiteLLM proxy configuration
+LITELLM_PROXY_URL = "ws://localhost:4000/v1/realtime?model=bedrock-sonic"
+LITELLM_API_KEY = "sk-12345" # Your LiteLLM API key
+
+
+class RealtimeClient:
+ """Client for LiteLLM realtime API with audio support."""
+
+ def __init__(self, url: str, api_key: str):
+ self.url = url
+ self.api_key = api_key
+ self.ws: Optional[websockets.WebSocketClientProtocol] = None
+ self.is_active = False
+ self.audio_queue = asyncio.Queue()
+ self.pyaudio = pyaudio.PyAudio()
+ self.input_stream = None
+ self.output_stream = None
+
+ async def connect(self):
+ """Connect to LiteLLM proxy realtime endpoint."""
+ print(f"Connecting to {self.url}...")
+
+ headers = {}
+ if self.api_key:
+ headers["Authorization"] = f"Bearer {self.api_key}"
+
+ self.ws = await websockets.connect(
+ self.url,
+ additional_headers=headers,
+ max_size=10 * 1024 * 1024, # 10MB max message size
+ )
+ self.is_active = True
+ print("✓ Connected to LiteLLM proxy")
+
+ async def send_session_update(self):
+ """Send session configuration."""
+ session_update = {
+ "type": "session.update",
+ "session": {
+ "instructions": "You are a friendly assistant. Keep your responses short and conversational.",
+ "voice": "matthew",
+ "temperature": 0.8,
+ "max_response_output_tokens": 1024,
+ "modalities": ["text", "audio"],
+ "input_audio_format": "pcm16",
+ "output_audio_format": "pcm16",
+ "turn_detection": {
+ "type": "server_vad",
+ "threshold": 0.5,
+ "prefix_padding_ms": 300,
+ "silence_duration_ms": 500,
+ },
+ },
+ }
+ await self.ws.send(json.dumps(session_update))
+ print("✓ Session configuration sent")
+
+ async def receive_messages(self):
+ """Receive and process messages from the server."""
+ try:
+ async for message in self.ws:
+ if not self.is_active:
+ break
+
+ try:
+ data = json.loads(message)
+ event_type = data.get("type")
+
+ if event_type == "session.created":
+ print(f"✓ Session created: {data.get('session', {}).get('id')}")
+
+ elif event_type == "response.created":
+ print("🤖 Assistant is responding...")
+
+ elif event_type == "response.text.delta":
+ # Print text transcription
+ delta = data.get("delta", "")
+ print(delta, end="", flush=True)
+
+ elif event_type == "response.audio.delta":
+ # Queue audio for playback
+ audio_b64 = data.get("delta", "")
+ if audio_b64:
+ audio_bytes = base64.b64decode(audio_b64)
+ await self.audio_queue.put(audio_bytes)
+
+ elif event_type == "response.text.done":
+ print() # New line after text
+
+ elif event_type == "response.done":
+ print("✓ Response complete")
+
+ elif event_type == "error":
+ print(f"❌ Error: {data.get('error', {})}")
+
+ else:
+ # Debug: print other event types
+ print(f"[{event_type}]", end=" ")
+
+ except json.JSONDecodeError:
+ print(f"Failed to parse message: {message[:100]}")
+
+ except websockets.exceptions.ConnectionClosed:
+ print("\n✗ Connection closed")
+ except Exception as e:
+ print(f"\n✗ Error receiving messages: {e}")
+ finally:
+ self.is_active = False
+
+ async def send_audio_chunk(self, audio_bytes: bytes):
+ """Send audio chunk to server."""
+ if not self.is_active or not self.ws:
+ return
+
+ audio_b64 = base64.b64encode(audio_bytes).decode("utf-8")
+ message = {
+ "type": "input_audio_buffer.append",
+ "audio": audio_b64,
+ }
+ await self.ws.send(json.dumps(message))
+
+ async def commit_audio_buffer(self):
+ """Commit the audio buffer to trigger processing."""
+ if not self.is_active or not self.ws:
+ return
+
+ message = {"type": "input_audio_buffer.commit"}
+ await self.ws.send(json.dumps(message))
+
+ async def capture_audio(self):
+ """Capture audio from microphone and send to server."""
+ print("\n🎤 Starting audio capture...")
+ print("Speak into your microphone. Press Ctrl+C to stop.\n")
+
+ self.input_stream = self.pyaudio.open(
+ format=FORMAT,
+ channels=CHANNELS,
+ rate=INPUT_SAMPLE_RATE,
+ input=True,
+ frames_per_buffer=CHUNK_SIZE,
+ )
+
+ try:
+ while self.is_active:
+ audio_data = self.input_stream.read(CHUNK_SIZE, exception_on_overflow=False)
+ await self.send_audio_chunk(audio_data)
+ await asyncio.sleep(0.01) # Small delay to prevent overwhelming
+ except Exception as e:
+ print(f"Error capturing audio: {e}")
+ finally:
+ if self.input_stream:
+ self.input_stream.stop_stream()
+ self.input_stream.close()
+
+ async def play_audio(self):
+ """Play audio responses from the server."""
+ print("🔊 Starting audio playback...")
+
+ self.output_stream = self.pyaudio.open(
+ format=FORMAT,
+ channels=CHANNELS,
+ rate=OUTPUT_SAMPLE_RATE,
+ output=True,
+ frames_per_buffer=CHUNK_SIZE,
+ )
+
+ try:
+ while self.is_active:
+ try:
+ audio_data = await asyncio.wait_for(
+ self.audio_queue.get(), timeout=0.1
+ )
+ if audio_data:
+ self.output_stream.write(audio_data)
+ except asyncio.TimeoutError:
+ continue
+ except Exception as e:
+ print(f"Error playing audio: {e}")
+ finally:
+ if self.output_stream:
+ self.output_stream.stop_stream()
+ self.output_stream.close()
+
+ async def close(self):
+ """Close the connection and cleanup."""
+ self.is_active = False
+
+ if self.ws:
+ await self.ws.close()
+
+ if self.input_stream:
+ self.input_stream.stop_stream()
+ self.input_stream.close()
+
+ if self.output_stream:
+ self.output_stream.stop_stream()
+ self.output_stream.close()
+
+ self.pyaudio.terminate()
+ print("\n✓ Connection closed")
+
+
+async def main():
+ """Main function to run the realtime client."""
+ print("=" * 80)
+ print("Bedrock Nova Sonic Realtime Client")
+ print("=" * 80)
+ print()
+
+ client = RealtimeClient(LITELLM_PROXY_URL, LITELLM_API_KEY)
+
+ try:
+ # Connect to server
+ await client.connect()
+
+ # Send session configuration
+ await client.send_session_update()
+
+ # Wait a moment for session to be established
+ await asyncio.sleep(0.5)
+
+ # Start tasks
+ receive_task = asyncio.create_task(client.receive_messages())
+ capture_task = asyncio.create_task(client.capture_audio())
+ playback_task = asyncio.create_task(client.play_audio())
+
+ # Wait for user to interrupt
+ await asyncio.gather(
+ receive_task,
+ capture_task,
+ playback_task,
+ return_exceptions=True,
+ )
+
+ except KeyboardInterrupt:
+ print("\n\n⚠ Interrupted by user")
+ except Exception as e:
+ print(f"\n❌ Error: {e}")
+ import traceback
+ traceback.print_exc()
+ finally:
+ await client.close()
+
+
+if __name__ == "__main__":
+ print("\nMake sure:")
+ print("1. LiteLLM proxy is running on port 4000")
+ print("2. Bedrock is configured in proxy_server_config.yaml")
+ print("3. AWS credentials are set")
+ print()
+
+ try:
+ asyncio.run(main())
+ except KeyboardInterrupt:
+ print("\n\nGoodbye!")
diff --git a/deploy/charts/litellm-helm/templates/deployment.yaml b/deploy/charts/litellm-helm/templates/deployment.yaml
index c3e0055e380..4ac5582d060 100644
--- a/deploy/charts/litellm-helm/templates/deployment.yaml
+++ b/deploy/charts/litellm-helm/templates/deployment.yaml
@@ -38,6 +38,10 @@ spec:
serviceAccountName: {{ include "litellm.serviceAccountName" . }}
securityContext:
{{- toYaml .Values.podSecurityContext | nindent 8 }}
+ {{- with .Values.extraInitContainers }}
+ initContainers:
+ {{- toYaml . | nindent 8 }}
+ {{- end }}
containers:
- name: {{ include "litellm.name" . }}
securityContext:
diff --git a/deploy/charts/litellm-helm/templates/migrations-job.yaml b/deploy/charts/litellm-helm/templates/migrations-job.yaml
index f8893a47afe..3459fa12d1c 100644
--- a/deploy/charts/litellm-helm/templates/migrations-job.yaml
+++ b/deploy/charts/litellm-helm/templates/migrations-job.yaml
@@ -35,6 +35,10 @@ spec:
{{- toYaml . | nindent 8 }}
{{- end }}
serviceAccountName: {{ include "litellm.serviceAccountName" . }}
+ {{- with .Values.migrationJob.extraInitContainers }}
+ initContainers:
+ {{- toYaml . | nindent 8 }}
+ {{- end }}
containers:
- name: prisma-migrations
image: "{{ .Values.image.repository }}:{{ .Values.image.tag | default (printf "main-%s" .Chart.AppVersion) }}"
diff --git a/deploy/charts/litellm-helm/values.yaml b/deploy/charts/litellm-helm/values.yaml
index 54271756998..cea25974bb0 100644
--- a/deploy/charts/litellm-helm/values.yaml
+++ b/deploy/charts/litellm-helm/values.yaml
@@ -234,6 +234,14 @@ db:
# instance. See the "postgresql" top level key for additional configuration.
deployStandalone: true
+# Lifecycle hooks for the LiteLLM container
+# Example:
+# lifecycle:
+# preStop:
+# exec:
+# command: ["/bin/sh", "-c", "sleep 10"]
+lifecycle: {}
+
# Settings for Bitnami postgresql chart (if db.deployStandalone is true, ignored
# otherwise)
postgresql:
@@ -273,6 +281,7 @@ migrationJob:
# cpu: 100m
# memory: 100Mi
extraContainers: []
+ extraInitContainers: []
# Hook configuration
hooks:
diff --git a/docker/Dockerfile.custom_ui b/docker/Dockerfile.custom_ui
index c437929a27e..57926bcd170 100644
--- a/docker/Dockerfile.custom_ui
+++ b/docker/Dockerfile.custom_ui
@@ -5,7 +5,8 @@ FROM ghcr.io/berriai/litellm:litellm_fwd_server_root_path-dev
WORKDIR /app
# Install Node.js and npm (adjust version as needed)
-RUN apt-get update && apt-get install -y nodejs npm
+RUN apt-get update && apt-get install -y nodejs npm && \
+ npm install -g npm@latest tar@latest
# Copy the UI source into the container
COPY ./ui/litellm-dashboard /app/ui/litellm-dashboard
diff --git a/docker/Dockerfile.database b/docker/Dockerfile.database
index 49655129506..24bf706434d 100644
--- a/docker/Dockerfile.database
+++ b/docker/Dockerfile.database
@@ -49,7 +49,8 @@ FROM $LITELLM_RUNTIME_IMAGE AS runtime
USER root
# Install runtime dependencies
-RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip libsndfile
+RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip libsndfile && \
+ npm install -g npm@latest tar@latest
WORKDIR /app
# Copy the current directory contents into the container at /app
diff --git a/docker/Dockerfile.dev b/docker/Dockerfile.dev
index 67966f9c739..ae557d4647f 100644
--- a/docker/Dockerfile.dev
+++ b/docker/Dockerfile.dev
@@ -61,7 +61,8 @@ RUN apt-get update && apt-get install -y --no-install-recommends \
libatomic1 \
nodejs \
npm \
- && rm -rf /var/lib/apt/lists/*
+ && rm -rf /var/lib/apt/lists/* \
+ && npm install -g npm@latest tar@latest
WORKDIR /app
diff --git a/docker/Dockerfile.non_root b/docker/Dockerfile.non_root
index 8c795f3b17f..3ef47607fca 100644
--- a/docker/Dockerfile.non_root
+++ b/docker/Dockerfile.non_root
@@ -47,7 +47,6 @@ RUN mkdir -p /var/lib/litellm/ui && \
if [ -f "/app/enterprise/enterprise_ui/enterprise_colors.json" ]; then \
cp /app/enterprise/enterprise_ui/enterprise_colors.json ./ui_colors.json; \
fi && \
- rm -f package-lock.json && \
npm install --legacy-peer-deps && \
npm run build && \
cp -r /app/ui/litellm-dashboard/out/* /var/lib/litellm/ui/ && \
@@ -104,7 +103,8 @@ RUN for i in 1 2 3; do \
done \
&& for i in 1 2 3; do \
apk add --no-cache python3 py3-pip bash openssl tzdata nodejs npm supervisor && break || sleep 5; \
- done
+ done \
+ && npm install -g npm@latest tar@latest
# Copy artifacts from builder
COPY --from=builder /app/requirements.txt /app/requirements.txt
@@ -170,12 +170,14 @@ RUN sed -i 's/\r$//' docker/entrypoint.sh && \
[ -n "$LITELLM_PROXY_EXTRAS_PATH" ] && chmod -R g+w $LITELLM_PROXY_EXTRAS_PATH || true && \
chmod -R g+rX $PRISMA_PATH && \
chmod -R g+rX /app/.cache && \
- mkdir -p /tmp/.npm /nonexistent /.npm && \
- prisma generate
+ mkdir -p /tmp/.npm /nonexistent /.npm
# Switch to non-root user for runtime
USER nobody
+# Generate Prisma client as nobody user to ensure correct file ownership
+RUN prisma generate
+
# Prisma runtime knobs for offline containers
ENV PRISMA_SKIP_POSTINSTALL_GENERATE=1 \
PRISMA_HIDE_UPDATE_MESSAGE=1 \
diff --git a/docs/my-website/blog/anthropic_opus_4_5_and_advanced_features/index.md b/docs/my-website/blog/anthropic_opus_4_5_and_advanced_features/index.md
index 7015918e924..8a54426dfb0 100644
--- a/docs/my-website/blog/anthropic_opus_4_5_and_advanced_features/index.md
+++ b/docs/my-website/blog/anthropic_opus_4_5_and_advanced_features/index.md
@@ -15,6 +15,7 @@ authors:
title: "CTO, LiteLLM"
url: https://www.linkedin.com/in/reffajnaahsi/
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
+description: "Guide to Claude Opus 4.5 and advanced features in LiteLLM: Tool Search, Programmatic Tool Calling, and Effort Parameter."
tags: [anthropic, claude, tool search, programmatic tool calling, effort, advanced features]
hide_table_of_contents: false
---
diff --git a/docs/my-website/blog/claude_opus_4_6/index.md b/docs/my-website/blog/claude_opus_4_6/index.md
new file mode 100644
index 00000000000..0397f1288f7
--- /dev/null
+++ b/docs/my-website/blog/claude_opus_4_6/index.md
@@ -0,0 +1,403 @@
+---
+slug: claude_opus_4_6
+title: "Day 0 Support: Claude Opus 4.6"
+date: 2026-02-05T10:00:00
+authors:
+ - name: Sameer Kankute
+ title: SWE @ LiteLLM (LLM Translation)
+ url: https://www.linkedin.com/in/sameer-kankute/
+ image_url: https://pbs.twimg.com/profile_images/2001352686994907136/ONgNuSk5_400x400.jpg
+ - name: Ishaan Jaff
+ title: "CTO, LiteLLM"
+ url: https://www.linkedin.com/in/reffajnaahsi/
+ image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
+ - name: Krrish Dholakia
+ title: "CEO, LiteLLM"
+ url: https://www.linkedin.com/in/krish-d/
+ image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
+description: "Day 0 support for Claude Opus 4.6 on LiteLLM AI Gateway - use across Anthropic, Azure, Vertex AI, and Bedrock."
+tags: [anthropic, claude, opus 4.6]
+hide_table_of_contents: false
+---
+
+import Tabs from '@theme/Tabs';
+import TabItem from '@theme/TabItem';
+
+LiteLLM now supports Claude Opus 4.6 on Day 0. Use it across Anthropic, Azure, Vertex AI, and Bedrock through the LiteLLM AI Gateway.
+
+## Docker Image
+
+```bash
+docker pull ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6
+```
+
+## Usage - Anthropic
+
+
+
+
+**1. Setup config.yaml**
+
+```yaml
+model_list:
+ - model_name: claude-opus-4-6
+ litellm_params:
+ model: anthropic/claude-opus-4-6
+ api_key: os.environ/ANTHROPIC_API_KEY
+```
+
+**2. Start the proxy**
+
+```bash
+docker run -d \
+ -p 4000:4000 \
+ -e ANTHROPIC_API_KEY=$ANTHROPIC_API_KEY \
+ -v $(pwd)/config.yaml:/app/config.yaml \
+ ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
+ --config /app/config.yaml
+```
+
+**3. Test it!**
+
+```bash
+curl --location 'http://0.0.0.0:4000/chat/completions' \
+--header 'Content-Type: application/json' \
+--header 'Authorization: Bearer $LITELLM_KEY' \
+--data '{
+ "model": "claude-opus-4-6",
+ "messages": [
+ {
+ "role": "user",
+ "content": "what llm are you"
+ }
+ ]
+}'
+```
+
+
+
+
+## Usage - Azure
+
+
+
+
+**1. Setup config.yaml**
+
+```yaml
+model_list:
+ - model_name: claude-opus-4-6
+ litellm_params:
+ model: azure_ai/claude-opus-4-6
+ api_key: os.environ/AZURE_AI_API_KEY
+ api_base: os.environ/AZURE_AI_API_BASE # https://.services.ai.azure.com
+```
+
+**2. Start the proxy**
+
+```bash
+docker run -d \
+ -p 4000:4000 \
+ -e AZURE_AI_API_KEY=$AZURE_AI_API_KEY \
+ -e AZURE_AI_API_BASE=$AZURE_AI_API_BASE \
+ -v $(pwd)/config.yaml:/app/config.yaml \
+ ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
+ --config /app/config.yaml
+```
+
+**3. Test it!**
+
+```bash
+curl --location 'http://0.0.0.0:4000/chat/completions' \
+--header 'Content-Type: application/json' \
+--header 'Authorization: Bearer $LITELLM_KEY' \
+--data '{
+ "model": "claude-opus-4-6",
+ "messages": [
+ {
+ "role": "user",
+ "content": "what llm are you"
+ }
+ ]
+}'
+```
+
+
+
+
+## Usage - Vertex AI
+
+
+
+
+**1. Setup config.yaml**
+
+```yaml
+model_list:
+ - model_name: claude-opus-4-6
+ litellm_params:
+ model: vertex_ai/claude-opus-4-6
+ vertex_project: os.environ/VERTEX_PROJECT
+ vertex_location: us-east5
+```
+
+**2. Start the proxy**
+
+```bash
+docker run -d \
+ -p 4000:4000 \
+ -e VERTEX_PROJECT=$VERTEX_PROJECT \
+ -e GOOGLE_APPLICATION_CREDENTIALS=/app/credentials.json \
+ -v $(pwd)/config.yaml:/app/config.yaml \
+ -v $(pwd)/credentials.json:/app/credentials.json \
+ ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
+ --config /app/config.yaml
+```
+
+**3. Test it!**
+
+```bash
+curl --location 'http://0.0.0.0:4000/chat/completions' \
+--header 'Content-Type: application/json' \
+--header 'Authorization: Bearer $LITELLM_KEY' \
+--data '{
+ "model": "claude-opus-4-6",
+ "messages": [
+ {
+ "role": "user",
+ "content": "what llm are you"
+ }
+ ]
+}'
+```
+
+
+
+
+## Usage - Bedrock
+
+
+
+
+**1. Setup config.yaml**
+
+```yaml
+model_list:
+ - model_name: claude-opus-4-6
+ litellm_params:
+ model: bedrock/anthropic.claude-opus-4-6-v1:0
+ aws_access_key_id: os.environ/AWS_ACCESS_KEY_ID
+ aws_secret_access_key: os.environ/AWS_SECRET_ACCESS_KEY
+ aws_region_name: us-east-1
+```
+
+**2. Start the proxy**
+
+```bash
+docker run -d \
+ -p 4000:4000 \
+ -e AWS_ACCESS_KEY_ID=$AWS_ACCESS_KEY_ID \
+ -e AWS_SECRET_ACCESS_KEY=$AWS_SECRET_ACCESS_KEY \
+ -v $(pwd)/config.yaml:/app/config.yaml \
+ ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
+ --config /app/config.yaml
+```
+
+**3. Test it!**
+
+```bash
+curl --location 'http://0.0.0.0:4000/chat/completions' \
+--header 'Content-Type: application/json' \
+--header 'Authorization: Bearer $LITELLM_KEY' \
+--data '{
+ "model": "claude-opus-4-6",
+ "messages": [
+ {
+ "role": "user",
+ "content": "what llm are you"
+ }
+ ]
+}'
+```
+
+
+
+
+## Compaction
+
+Litellm supports enabling compaction for the new claude-opus-4-6.
+
+### Enabling Compaction
+
+To enable compaction, add the `context_management` parameter with the `compact_20260112` edit type:
+
+```bash
+curl --location 'http://0.0.0.0:4000/chat/completions' \
+--header 'Content-Type: application/json' \
+--header 'Authorization: Bearer $LITELLM_KEY' \
+--data '{
+ "model": "claude-opus-4-6",
+ "messages": [
+ {
+ "role": "user",
+ "content": "What is the weather in San Francisco?"
+ }
+ ],
+ "context_management": {
+ "edits": [
+ {
+ "type": "compact_20260112"
+ }
+ ]
+ },
+ "max_tokens": 100
+}'
+```
+All the parameters supported for context_management by anthropic are supported and can be directly added. Litellm automatically adds the `compact-2026-01-12` beta header in the request.
+
+
+### Response with Compaction Block
+
+The response will include the compaction summary in `provider_specific_fields.compaction_blocks`:
+
+```json
+{
+ "id": "chatcmpl-a6c105a3-4b25-419e-9551-c800633b6cb2",
+ "created": 1770357619,
+ "model": "claude-opus-4-6",
+ "object": "chat.completion",
+ "choices": [
+ {
+ "finish_reason": "length",
+ "index": 0,
+ "message": {
+ "content": "I don't have access to real-time data, so I can't provide the current weather in San Francisco. To get up-to-date weather information, I'd recommend checking:\n\n- **Weather websites** like weather.com, accuweather.com, or wunderground.com\n- **Search engines** – just Google \"San Francisco weather\"\n- **Weather apps** on your phone (e.g., Apple Weather, Google Weather)\n- **National",
+ "role": "assistant",
+ "provider_specific_fields": {
+ "compaction_blocks": [
+ {
+ "type": "compaction",
+ "content": "Summary of the conversation: The user requested help building a web scraper..."
+ }
+ ]
+ }
+ }
+ }
+ ],
+ "usage": {
+ "completion_tokens": 100,
+ "prompt_tokens": 86,
+ "total_tokens": 186
+ }
+}
+```
+
+### Using Compaction Blocks in Follow-up Requests
+
+To continue the conversation with compaction, include the compaction block in the assistant message's `provider_specific_fields`:
+
+```bash
+curl --location 'http://0.0.0.0:4000/chat/completions' \
+--header 'Content-Type: application/json' \
+--header 'Authorization: Bearer $LITELLM_KEY' \
+--data '{
+ "model": "claude-opus-4-6",
+ "messages": [
+ {
+ "role": "user",
+ "content": "How can I build a web scraper?"
+ },
+ {
+ "role": "assistant",
+ "content": [
+ {
+ "type": "text",
+ "text": "Certainly! To build a basic web scraper, you'll typically use a programming language like Python along with libraries such as `requests` (for fetching web pages) and `BeautifulSoup` (for parsing HTML). Here's a basic example:\n\n```python\nimport requests\nfrom bs4 import BeautifulSoup\n\nurl = 'https://example.com'\nresponse = requests.get(url)\nsoup = BeautifulSoup(response.text, 'html.parser')\n\n# Extract and print all text\ntext = soup.get_text()\nprint(text)\n```\n\nLet me know what you're interested in scraping or if you need help with a specific website!"
+ }
+ ],
+ "provider_specific_fields": {
+ "compaction_blocks": [
+ {
+ "type": "compaction",
+ "content": "Summary of the conversation: The user asked how to build a web scraper, and the assistant gave an overview using Python with requests and BeautifulSoup."
+ }
+ ]
+ }
+ },
+ {
+ "role": "user",
+ "content": "How do I use it to scrape product prices?"
+ }
+ ],
+ "context_management": {
+ "edits": [
+ {
+ "type": "compact_20260112"
+ }
+ ]
+ },
+ "max_tokens": 100
+}'
+```
+
+### Streaming Support
+
+Compaction blocks are also supported in streaming mode. You'll receive:
+- `compaction_start` event when a compaction block begins
+- `compaction_delta` events with the compaction content
+- The accumulated `compaction_blocks` in `provider_specific_fields`
+
+
+## Adaptive Thinking
+
+LiteLLM supports adaptive thinking through the `reasoning_effort` parameter:
+
+```bash
+curl --location 'http://0.0.0.0:4000/chat/completions' \
+--header 'Content-Type: application/json' \
+--header 'Authorization: Bearer $LITELLM_KEY' \
+--data '{
+ "model": "claude-opus-4-6",
+ "messages": [
+ {
+ "role": "user",
+ "content": "Solve this complex problem: What is the optimal strategy for..."
+ }
+ ],
+ "reasoning_effort": "high"
+}'
+```
+
+## Effort Levels
+
+Four effort levels available: `low`, `medium`, `high` (default), and `max`. Pass directly via the `output_config` parameter:
+
+```bash
+curl --location 'http://0.0.0.0:4000/chat/completions' \
+--header 'Content-Type: application/json' \
+--header 'Authorization: Bearer $LITELLM_KEY' \
+--data '{
+ "model": "claude-opus-4-6",
+ "messages": [
+ {
+ "role": "user",
+ "content": "Explain quantum computing"
+ }
+ ],
+ "output_config": {
+ "effort": "medium"
+ }
+
+}'
+```
+
+You can use reasoning effort plus output_config to have more control on the model.
+
+## 1M Token Context (Beta)
+
+Opus 4.6 supports 1M token context. Premium pricing applies for prompts exceeding 200k tokens ($10/$37.50 per million input/output tokens). LiteLLM supports cost calculations for 1M token contexts.
+
+## US-Only Inference
+
+Available at 1.1× token pricing. LiteLLM supports this pricing model.
+
diff --git a/docs/my-website/blog/gemini_3/index.md b/docs/my-website/blog/gemini_3/index.md
index 26dbc2d02b5..7263acc12c9 100644
--- a/docs/my-website/blog/gemini_3/index.md
+++ b/docs/my-website/blog/gemini_3/index.md
@@ -15,6 +15,7 @@ authors:
title: "CTO, LiteLLM"
url: https://www.linkedin.com/in/reffajnaahsi/
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
+description: "Common questions and best practices for using gemini-3-pro-preview with LiteLLM Proxy and SDK."
tags: [gemini, day 0 support, llms]
hide_table_of_contents: false
---
diff --git a/docs/my-website/blog/gemini_3_flash/index.md b/docs/my-website/blog/gemini_3_flash/index.md
index 6cb8ddad992..830c21e5f66 100644
--- a/docs/my-website/blog/gemini_3_flash/index.md
+++ b/docs/my-website/blog/gemini_3_flash/index.md
@@ -15,6 +15,7 @@ authors:
title: "CTO, LiteLLM"
url: https://www.linkedin.com/in/reffajnaahsi/
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
+description: "Guide to using Gemini 3 Flash on LiteLLM Proxy and SDK with day 0 support."
tags: [gemini, day 0 support, llms]
hide_table_of_contents: false
---
diff --git a/docs/my-website/blog/litellm_observatory/index.md b/docs/my-website/blog/litellm_observatory/index.md
new file mode 100644
index 00000000000..f9944be8c27
--- /dev/null
+++ b/docs/my-website/blog/litellm_observatory/index.md
@@ -0,0 +1,136 @@
+---
+slug: litellm-observatory
+title: "LiteLLM Observatory: Raising the Bar for Release Reliability"
+date: 2026-02-06T10:00:00
+authors:
+ - name: Alexsander Hamir
+ title: "Performance Engineer, LiteLLM"
+ url: https://www.linkedin.com/in/alexsander-baptista/
+ image_url: https://github.com/AlexsanderHamir.png
+ - name: Krrish Dholakia
+ title: "CEO, LiteLLM"
+ url: https://www.linkedin.com/in/krish-d/
+ image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
+ - name: Ishaan Jaff
+ title: "CTO, LiteLLM"
+ url: https://www.linkedin.com/in/reffajnaahsi/
+ image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
+description: "How we built a long-running, release-validation system to catch regressions before they reach users."
+tags: [testing, observability, reliability, releases]
+hide_table_of_contents: false
+---
+
+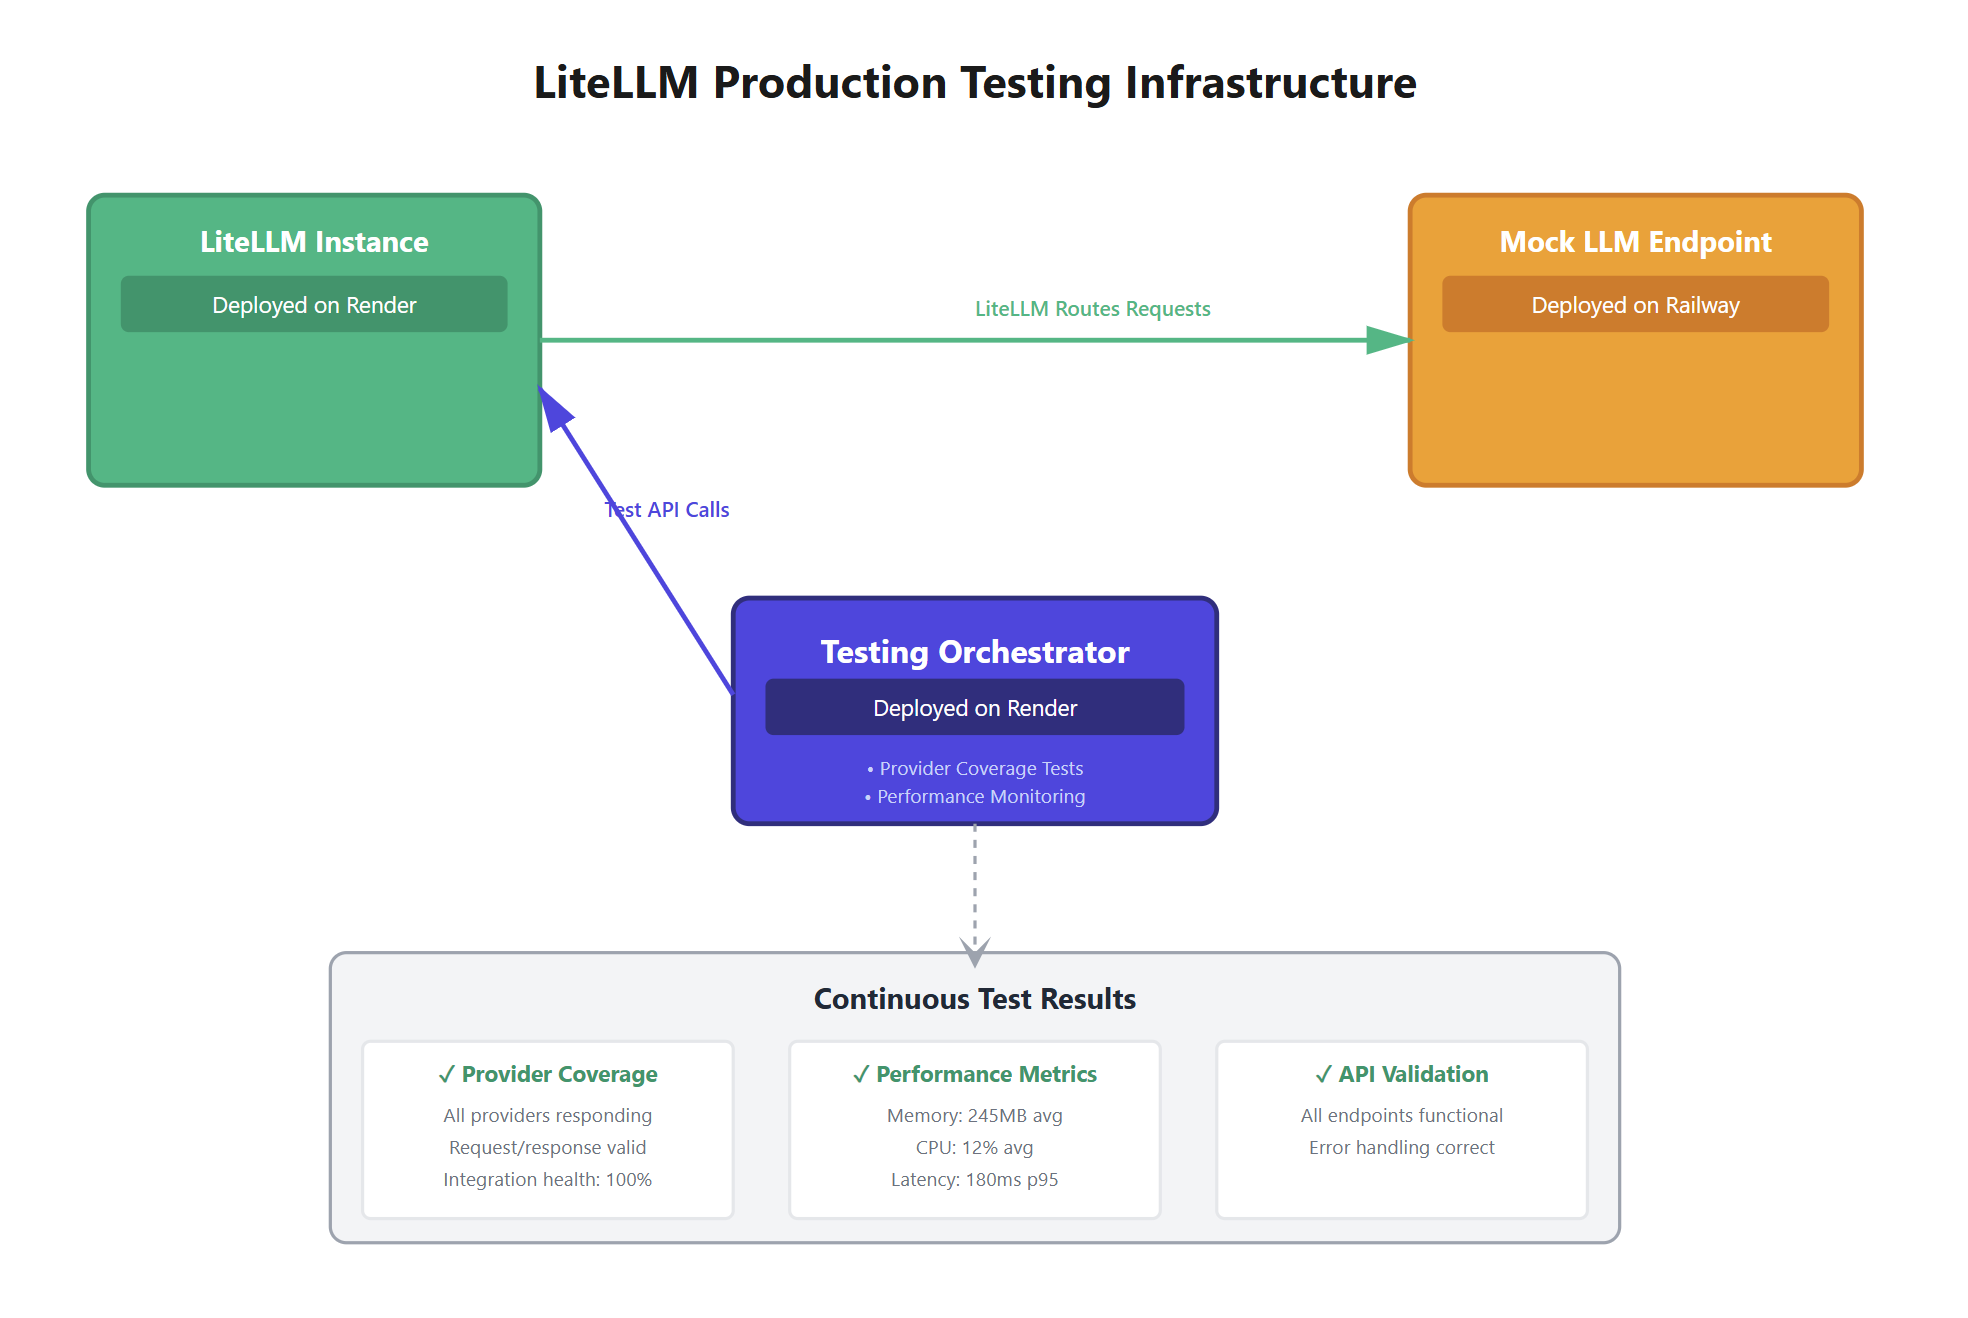
+
+# LiteLLM Observatory: Raising the Bar for Release Reliability
+
+As LiteLLM adoption has grown, so have expectations around reliability, performance, and operational safety. Meeting those expectations requires more than correctness-focused tests, it requires validating how the system behaves over time, under real-world conditions.
+
+This post introduces **LiteLLM Observatory**, a long-running release-validation system we built to catch regressions before they reach users.
+
+---
+
+## Why We Built the Observatory
+
+LiteLLM operates at the intersection of external providers, long-lived network connections, and high-throughput workloads. While our unit and integration tests do an excellent job validating correctness, they are not designed to surface issues that only appear after extended operation.
+
+A subtle lifecycle edge case discovered in v1.81.3 reinforced the need for stronger release validation in this area.
+
+---
+
+## A Real-World Lifecycle Edge Case
+
+In v1.81.3, we shipped a fix for an HTTP client memory leak. The change passed unit and integration tests and behaved correctly in short-lived runs.
+
+The issue that surfaced was not caused by a single incorrect line of logic, but by how multiple components interacted over time:
+
+- A cached `httpx` client was configured with a 1-hour TTL
+- When the cache expired, the underlying HTTP connection was closed as expected
+- A higher-level client continued to hold a reference to that connection
+- Subsequent requests failed with:
+
+```
+Cannot send a request, as the client has been closed
+```
+
+Our focus moving forward is on being the first to detect issues, even when they aren’t covered by unit tests. LiteLLM Observatory is designed to surface latency regressions, OOMs, and failure modes that only appear under real traffic patterns in **our own production deployments** during release validation.
+
+
+---
+
+## Introducing LiteLLM Observatory
+
+To systematically address this class of issues, we built **LiteLLM Observatory**.
+
+The Observatory is a long-running testing orchestrator used during release validation to exercise LiteLLM under production-like conditions for extended periods of time.
+
+Its core goals are:
+
+- Validate behavior over hours, not minutes
+- Turn production learnings into permanent release safeguards
+
+---
+
+### How the Observatory Works
+
+[LiteLLM Observatory](https://github.com/BerriAI/litellm-observatory) is a testing service that runs long-running tests against our LiteLLM deployments. We trigger tests by sending API requests, and results are automatically sent to Slack when tests complete.
+
+#### How Tests Run
+
+1. **Start a Test**: We send a request to the Observatory API with:
+ - Which LiteLLM deployment to test (URL and API key)
+ - Which test to run (e.g., `TestOAIAzureRelease`)
+ - Test settings (which models to test, how long to run, failure thresholds)
+
+2. **Smart Queueing**:
+ - The system checks whether we are attempting to run the exact same test more than once
+ - If a duplicate test is already running or queued, we receive an error to avoid wasting resources
+ - Otherwise, the test is added to a queue and runs when capacity is available (up to 5 tests can run concurrently by default)
+
+3. **Instant Response**: The API responds immediately—we do not wait for the test to finish. Tests may run for hours, but the request itself completes in milliseconds.
+
+4. **Background Execution**:
+ - The test runs in the background, issuing requests against our LiteLLM deployment
+ - It tracks request success and failure rates over time
+ - When the test completes, results are automatically posted to our Slack channel
+
+#### Example: The OpenAI / Azure Reliability Test
+
+The `TestOAIAzureRelease` test is designed to catch a class of bugs that only surface after sustained runtime:
+
+- **Duration**: Runs continuously for 3 hours
+- **Behavior**: Cycles through specified models (such as `gpt-4` and `gpt-3.5-turbo`), issuing requests continuously
+- **Why 3 Hours**: This helps catch issues where HTTP clients degrade or fail after extended use (for example, a bug observed in LiteLLM v1.81.3)
+- **Pass / Fail Criteria**: The test passes if fewer than 1% of requests fail. If the failure rate exceeds 1%, the test fails and we are notified in Slack
+- **Key Detail**: The same HTTP client is reused for the entire run, allowing us to detect lifecycle-related bugs that only appear under prolonged reuse
+
+#### When We Use It
+
+- **Before Deployments**: Run tests before promoting a new LiteLLM version to production
+- **Routine Validation**: Schedule regular runs (daily or weekly) to catch regressions early
+- **Issue Investigation**: Run tests on demand when we suspect a deployment issue
+- **Long-Running Failure Detection**: Identify bugs that only appear under sustained load, beyond what short smoke tests can reveal
+
+
+### Complementing Unit Tests
+
+Unit tests remain a foundational part of our development process. They are fast and precise, but they don’t cover:
+
+- Real provider behavior
+- Long-lived network interactions
+- Resource lifecycle edge cases
+- Time-dependent regressions
+
+LiteLLM Observatory complements unit tests by validating the system as it actually runs in production-like environments.
+
+---
+
+### Looking Ahead
+
+Reliability is an ongoing investment.
+
+LiteLLM Observatory is one of several systems we’re building to continuously raise the bar on release quality and operational safety. As LiteLLM evolves, so will our validation tooling, informed by real-world usage and lessons learned.
+
+We’ll continue to share those improvements openly as we go.
+```
+
diff --git a/docs/my-website/blog/sub_millisecond_proxy_overhead/index.md b/docs/my-website/blog/sub_millisecond_proxy_overhead/index.md
new file mode 100644
index 00000000000..1857383363c
--- /dev/null
+++ b/docs/my-website/blog/sub_millisecond_proxy_overhead/index.md
@@ -0,0 +1,92 @@
+---
+slug: sub-millisecond-proxy-overhead
+title: "Achieving Sub-Millisecond Proxy Overhead"
+date: 2026-02-02T10:00:00
+authors:
+ - name: Alexsander Hamir
+ title: "Performance Engineer, LiteLLM"
+ url: https://www.linkedin.com/in/alexsander-baptista/
+ image_url: https://github.com/AlexsanderHamir.png
+ - name: Krrish Dholakia
+ title: "CEO, LiteLLM"
+ url: https://www.linkedin.com/in/krish-d/
+ image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
+ - name: Ishaan Jaff
+ title: "CTO, LiteLLM"
+ url: https://www.linkedin.com/in/reffajnaahsi/
+ image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
+description: "Our Q1 performance target and architectural direction for achieving sub-millisecond proxy overhead on modest hardware."
+tags: [performance, architecture]
+hide_table_of_contents: false
+---
+
+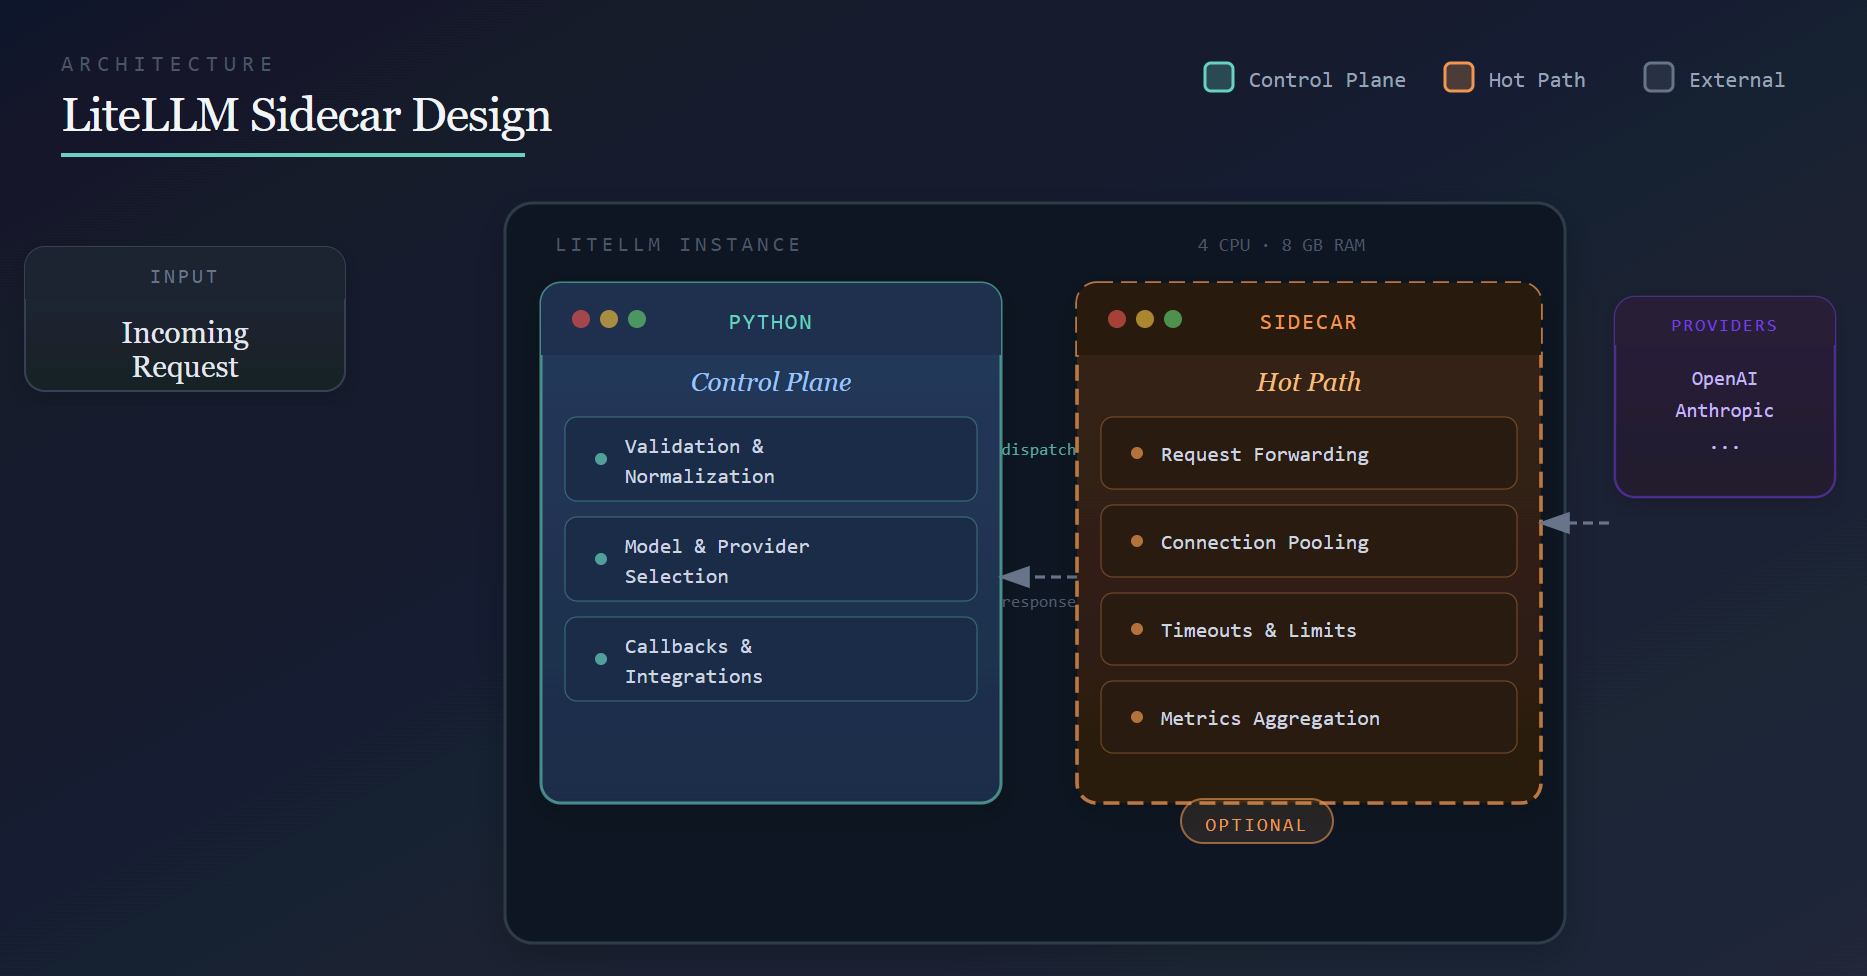
+
+# Achieving Sub-Millisecond Proxy Overhead
+
+## Introduction
+
+Our Q1 performance target is to aggressively move toward sub-millisecond proxy overhead on a single instance with 4 CPUs and 8 GB of RAM, and to continue pushing that boundary over time. Our broader goal is to make LiteLLM inexpensive to deploy, lightweight, and fast. This post outlines the architectural direction behind that effort.
+
+Proxy overhead refers to the latency introduced by LiteLLM itself, independent of the upstream provider.
+
+To measure it, we run the same workload directly against the provider and through LiteLLM at identical QPS (for example, 1,000 QPS) and compare the latency delta. To reduce noise, the load generator, LiteLLM, and a mock LLM endpoint all run on the same machine, ensuring the difference reflects proxy overhead rather than network latency.
+
+---
+
+## Where We're Coming From
+
+Under the same benchmark originally conducted by [TensorZero](https://www.tensorzero.com/docs/gateway/benchmarks), LiteLLM previously failed at around 1,000 QPS.
+
+That is no longer the case. Today, LiteLLM can be stress-tested at 1,000 QPS with no failures and can scale up to 5,000 QPS without failures on a 4-CPU, 8-GB RAM single instance setup.
+
+This establishes a more up to date baseline and provides useful context as we continue working on proxy overhead and overall performance.
+
+---
+
+## Design Choice
+
+Achieving sub-millisecond proxy overhead with a Python-based system requires being deliberate about where work happens.
+
+Python is a strong fit for flexibility and extensibility: provider abstraction, configuration-driven routing, and a rich callback ecosystem. These are areas where development velocity and correctness matter more than raw throughput.
+
+At higher request rates, however, certain classes of work become expensive when executed inside the Python process on every request. Rather than rewriting LiteLLM or introducing complex deployment requirements, we adopt an optional **sidecar architecture**.
+
+This architectural change is how we intend to make LiteLLM **permanently fast**. While it supports our near-term performance targets, it is a long-term investment.
+
+Python continues to own:
+
+- Request validation and normalization
+- Model and provider selection
+- Callbacks and integrations
+
+The sidecar owns **performance-critical execution**, such as:
+
+- Efficient request forwarding
+- Connection reuse and pooling
+- Enforcing timeouts and limits
+- Aggregating high-frequency metrics
+
+This separation allows each component to focus on what it does best: Python acts as the control plane, while the sidecar handles the hot path.
+
+---
+
+### Why the Sidecar Is Optional
+
+The sidecar is intentionally **optional**.
+
+This allows us to ship it incrementally, validate it under real-world workloads, and avoid making it a hard dependency before it is fully battle-tested across all LiteLLM features.
+
+Just as importantly, this ensures that self-hosting LiteLLM remains simple. The sidecar is bundled and started automatically, requires no additional infrastructure, and can be disabled entirely. From a user's perspective, LiteLLM continues to behave like a single service.
+
+As of today, the sidecar is an optimization, not a requirement.
+
+---
+
+## Conclusion
+
+Sub-millisecond proxy overhead is not achieved through a single optimization, but through architectural changes.
+
+By keeping Python focused on orchestration and extensibility, and offloading performance-critical execution to a sidecar, we establish a foundation for making LiteLLM **permanently fast over time**—even on modest hardware such as a 1-CPU, 2-GB RAM instance, while keeping deployment and self-hosting simple.
+
+This work extends beyond Q1, and we will continue sharing benchmarks and updates as the architecture evolves.
diff --git a/docs/my-website/docs/a2a.md b/docs/my-website/docs/a2a.md
index d7145e4b83c..b1166a7809c 100644
--- a/docs/my-website/docs/a2a.md
+++ b/docs/my-website/docs/a2a.md
@@ -68,116 +68,9 @@ Follow [this guide, to add your pydantic ai agent to LiteLLM Agent Gateway](./pr
## Invoking your Agents
-Use the [A2A Python SDK](https://pypi.org/project/a2a/) to invoke agents through LiteLLM.
-
-This example shows how to:
-1. **List available agents** - Query `/v1/agents` to see which agents your key can access
-2. **Select an agent** - Pick an agent from the list
-3. **Invoke via A2A** - Use the A2A protocol to send messages to the agent
-
-```python showLineNumbers title="invoke_a2a_agent.py"
-from uuid import uuid4
-import httpx
-import asyncio
-from a2a.client import A2ACardResolver, A2AClient
-from a2a.types import MessageSendParams, SendMessageRequest
-
-# === CONFIGURE THESE ===
-LITELLM_BASE_URL = "http://localhost:4000" # Your LiteLLM proxy URL
-LITELLM_VIRTUAL_KEY = "sk-1234" # Your LiteLLM Virtual Key
-# =======================
-
-async def main():
- headers = {"Authorization": f"Bearer {LITELLM_VIRTUAL_KEY}"}
-
- async with httpx.AsyncClient(headers=headers) as client:
- # Step 1: List available agents
- response = await client.get(f"{LITELLM_BASE_URL}/v1/agents")
- agents = response.json()
-
- print("Available agents:")
- for agent in agents:
- print(f" - {agent['agent_name']} (ID: {agent['agent_id']})")
-
- if not agents:
- print("No agents available for this key")
- return
-
- # Step 2: Select an agent and invoke it
- selected_agent = agents[0]
- agent_id = selected_agent["agent_id"]
- agent_name = selected_agent["agent_name"]
- print(f"\nInvoking: {agent_name}")
-
- # Step 3: Use A2A protocol to invoke the agent
- base_url = f"{LITELLM_BASE_URL}/a2a/{agent_id}"
- resolver = A2ACardResolver(httpx_client=client, base_url=base_url)
- agent_card = await resolver.get_agent_card()
- a2a_client = A2AClient(httpx_client=client, agent_card=agent_card)
-
- request = SendMessageRequest(
- id=str(uuid4()),
- params=MessageSendParams(
- message={
- "role": "user",
- "parts": [{"kind": "text", "text": "Hello, what can you do?"}],
- "messageId": uuid4().hex,
- }
- ),
- )
- response = await a2a_client.send_message(request)
- print(f"Response: {response.model_dump(mode='json', exclude_none=True, indent=4)}")
-
-if __name__ == "__main__":
- asyncio.run(main())
-```
-
-### Streaming Responses
-
-For streaming responses, use `send_message_streaming`:
-
-```python showLineNumbers title="invoke_a2a_agent_streaming.py"
-from uuid import uuid4
-import httpx
-import asyncio
-from a2a.client import A2ACardResolver, A2AClient
-from a2a.types import MessageSendParams, SendStreamingMessageRequest
-
-# === CONFIGURE THESE ===
-LITELLM_BASE_URL = "http://localhost:4000" # Your LiteLLM proxy URL
-LITELLM_VIRTUAL_KEY = "sk-1234" # Your LiteLLM Virtual Key
-LITELLM_AGENT_NAME = "ij-local" # Agent name registered in LiteLLM
-# =======================
-
-async def main():
- base_url = f"{LITELLM_BASE_URL}/a2a/{LITELLM_AGENT_NAME}"
- headers = {"Authorization": f"Bearer {LITELLM_VIRTUAL_KEY}"}
-
- async with httpx.AsyncClient(headers=headers) as httpx_client:
- # Resolve agent card and create client
- resolver = A2ACardResolver(httpx_client=httpx_client, base_url=base_url)
- agent_card = await resolver.get_agent_card()
- client = A2AClient(httpx_client=httpx_client, agent_card=agent_card)
-
- # Send a streaming message
- request = SendStreamingMessageRequest(
- id=str(uuid4()),
- params=MessageSendParams(
- message={
- "role": "user",
- "parts": [{"kind": "text", "text": "Hello, what can you do?"}],
- "messageId": uuid4().hex,
- }
- ),
- )
-
- # Stream the response
- async for chunk in client.send_message_streaming(request):
- print(chunk.model_dump(mode="json", exclude_none=True))
-
-if __name__ == "__main__":
- asyncio.run(main())
-```
+See the [Invoking A2A Agents](./a2a_invoking_agents) guide to learn how to call your agents using:
+- **A2A SDK** - Native A2A protocol with full support for tasks and artifacts
+- **OpenAI SDK** - Familiar `/chat/completions` interface with `a2a/` model prefix
## Tracking Agent Logs
@@ -193,6 +86,120 @@ The logs show:
style={{width: '100%', display: 'block', margin: '2rem auto'}}
/>
+
+## Forwarding LiteLLM Context Headers
+
+When LiteLLM invokes your A2A agent, it sends special headers that enable:
+- **Trace Grouping**: All LLM calls from the same agent execution appear under one trace
+- **Agent Spend Tracking**: Costs are attributed to the specific agent
+
+| Header | Purpose |
+|--------|---------|
+| `X-LiteLLM-Trace-Id` | Links all LLM calls to the same execution flow |
+| `X-LiteLLM-Agent-Id` | Attributes spend to the correct agent |
+
+
+To enable these features, your A2A server must **forward these headers** to any LLM calls it makes back to LiteLLM.
+
+### Implementation Steps
+
+**Step 1: Extract headers from incoming A2A request**
+```python def get_litellm_headers(request) -> dict:
+ """Extract X-LiteLLM-* headers from incoming A2A request."""
+ all_headers = request.call_context.state.get('headers', {})
+ return {
+ k: v for k, v in all_headers.items()
+ if k.lower().startswith('x-litellm-')
+ }
+```
+
+**Step 2: Forward headers to your LLM calls**
+Pass the extracted headers when making calls back to LiteLLM:
+
+
+
+```python from openai import OpenAI
+
+headers = get_litellm_headers(request)
+
+client = OpenAI(
+ api_key="sk-your-litellm-key",
+ base_url="http://localhost:4000",
+ default_headers=headers, # Forward headers
+)
+
+response = client.chat.completions.create(
+ model="gpt-4o",
+ messages=[{"role": "user", "content": "Hello"}]
+)
+```
+
+
+
+
+```python
+from langchain_openai import ChatOpenAI
+
+headers = get_litellm_headers(request)
+
+llm = ChatOpenAI(
+ model="gpt-4o",
+ openai_api_key="sk-your-litellm-key",
+ base_url="http://localhost:4000",
+ default_headers=headers, # Forward headers
+)
+```
+
+
+
+```python
+import litellm
+
+headers = get_litellm_headers(request)
+
+response = litellm.completion(
+ model="gpt-4o",
+ messages=[{"role": "user", "content": "Hello"}],
+ api_base="http://localhost:4000",
+ extra_headers=headers, # Forward headers
+)
+```
+
+
+
+```python
+import httpx
+
+headers = get_litellm_headers(request)
+headers["Authorization"] = "Bearer sk-your-litellm-key"
+
+response = httpx.post(
+ "http://localhost:4000/v1/chat/completions",
+ headers=headers,
+ json={"model": "gpt-4o", "messages": [{"role": "user", "content": "Hello"}]}
+)
+```
+
+
+
+### Result
+
+With header forwarding enabled, you'll see:
+
+**Trace Grouping in Langfuse:**
+
+
+
+**Agent Spend Attribution:**
+
+
+
## API Reference
### Endpoint
diff --git a/docs/my-website/docs/a2a_invoking_agents.md b/docs/my-website/docs/a2a_invoking_agents.md
new file mode 100644
index 00000000000..3bb248e4561
--- /dev/null
+++ b/docs/my-website/docs/a2a_invoking_agents.md
@@ -0,0 +1,280 @@
+import Tabs from '@theme/Tabs';
+import TabItem from '@theme/TabItem';
+
+# Invoking A2A Agents
+
+Learn how to invoke A2A agents through LiteLLM using different methods.
+
+:::tip Deploy Your Own A2A Agent
+
+Want to test with your own agent? Deploy this template A2A agent powered by Google Gemini:
+
+[**shin-bot-litellm/a2a-gemini-agent**](https://github.com/shin-bot-litellm/a2a-gemini-agent) - Simple deployable A2A agent with streaming support
+
+:::
+
+## A2A SDK
+
+Use the [A2A Python SDK](https://pypi.org/project/a2a-sdk) to invoke agents through LiteLLM using the A2A protocol.
+
+### Non-Streaming
+
+This example shows how to:
+1. **List available agents** - Query `/v1/agents` to see which agents your key can access
+2. **Select an agent** - Pick an agent from the list
+3. **Invoke via A2A** - Use the A2A protocol to send messages to the agent
+
+```python showLineNumbers title="invoke_a2a_agent.py"
+from uuid import uuid4
+import httpx
+import asyncio
+from a2a.client import A2ACardResolver, A2AClient
+from a2a.types import MessageSendParams, SendMessageRequest
+
+# === CONFIGURE THESE ===
+LITELLM_BASE_URL = "http://localhost:4000" # Your LiteLLM proxy URL
+LITELLM_VIRTUAL_KEY = "sk-1234" # Your LiteLLM Virtual Key
+# =======================
+
+async def main():
+ headers = {"Authorization": f"Bearer {LITELLM_VIRTUAL_KEY}"}
+
+ async with httpx.AsyncClient(headers=headers) as client:
+ # Step 1: List available agents
+ response = await client.get(f"{LITELLM_BASE_URL}/v1/agents")
+ agents = response.json()
+
+ print("Available agents:")
+ for agent in agents:
+ print(f" - {agent['agent_name']} (ID: {agent['agent_id']})")
+
+ if not agents:
+ print("No agents available for this key")
+ return
+
+ # Step 2: Select an agent and invoke it
+ selected_agent = agents[0]
+ agent_id = selected_agent["agent_id"]
+ agent_name = selected_agent["agent_name"]
+ print(f"\nInvoking: {agent_name}")
+
+ # Step 3: Use A2A protocol to invoke the agent
+ base_url = f"{LITELLM_BASE_URL}/a2a/{agent_id}"
+ resolver = A2ACardResolver(httpx_client=client, base_url=base_url)
+ agent_card = await resolver.get_agent_card()
+ a2a_client = A2AClient(httpx_client=client, agent_card=agent_card)
+
+ request = SendMessageRequest(
+ id=str(uuid4()),
+ params=MessageSendParams(
+ message={
+ "role": "user",
+ "parts": [{"kind": "text", "text": "Hello, what can you do?"}],
+ "messageId": uuid4().hex,
+ }
+ ),
+ )
+ response = await a2a_client.send_message(request)
+ print(f"Response: {response.model_dump(mode='json', exclude_none=True, indent=4)}")
+
+if __name__ == "__main__":
+ asyncio.run(main())
+```
+
+### Streaming
+
+For streaming responses, use `send_message_streaming`:
+
+```python showLineNumbers title="invoke_a2a_agent_streaming.py"
+from uuid import uuid4
+import httpx
+import asyncio
+from a2a.client import A2ACardResolver, A2AClient
+from a2a.types import MessageSendParams, SendStreamingMessageRequest
+
+# === CONFIGURE THESE ===
+LITELLM_BASE_URL = "http://localhost:4000" # Your LiteLLM proxy URL
+LITELLM_VIRTUAL_KEY = "sk-1234" # Your LiteLLM Virtual Key
+LITELLM_AGENT_NAME = "ij-local" # Agent name registered in LiteLLM
+# =======================
+
+async def main():
+ base_url = f"{LITELLM_BASE_URL}/a2a/{LITELLM_AGENT_NAME}"
+ headers = {"Authorization": f"Bearer {LITELLM_VIRTUAL_KEY}"}
+
+ async with httpx.AsyncClient(headers=headers) as httpx_client:
+ # Resolve agent card and create client
+ resolver = A2ACardResolver(httpx_client=httpx_client, base_url=base_url)
+ agent_card = await resolver.get_agent_card()
+ client = A2AClient(httpx_client=httpx_client, agent_card=agent_card)
+
+ # Send a streaming message
+ request = SendStreamingMessageRequest(
+ id=str(uuid4()),
+ params=MessageSendParams(
+ message={
+ "role": "user",
+ "parts": [{"kind": "text", "text": "Tell me a long story"}],
+ "messageId": uuid4().hex,
+ }
+ ),
+ )
+
+ # Stream the response
+ async for chunk in client.send_message_streaming(request):
+ print(chunk.model_dump(mode="json", exclude_none=True))
+
+if __name__ == "__main__":
+ asyncio.run(main())
+```
+
+## /chat/completions API (OpenAI SDK)
+
+You can also invoke A2A agents using the familiar OpenAI SDK by using the `a2a/` model prefix.
+
+### Non-Streaming
+
+
+
+
+```python showLineNumbers title="openai_non_streaming.py"
+import openai
+
+client = openai.OpenAI(
+ api_key="sk-1234", # Your LiteLLM Virtual Key
+ base_url="http://localhost:4000" # Your LiteLLM proxy URL
+)
+
+response = client.chat.completions.create(
+ model="a2a/my-agent", # Use a2a/ prefix with your agent name
+ messages=[
+ {"role": "user", "content": "Hello, what can you do?"}
+ ]
+)
+
+print(response.choices[0].message.content)
+```
+
+
+
+
+```typescript showLineNumbers title="openai_non_streaming.ts"
+import OpenAI from 'openai';
+
+const client = new OpenAI({
+ apiKey: 'sk-1234', // Your LiteLLM Virtual Key
+ baseURL: 'http://localhost:4000' // Your LiteLLM proxy URL
+});
+
+const response = await client.chat.completions.create({
+ model: 'a2a/my-agent', // Use a2a/ prefix with your agent name
+ messages: [
+ { role: 'user', content: 'Hello, what can you do?' }
+ ]
+});
+
+console.log(response.choices[0].message.content);
+```
+
+
+
+
+```bash showLineNumbers title="curl_non_streaming.sh"
+curl -X POST http://localhost:4000/v1/chat/completions \
+ -H "Authorization: Bearer sk-1234" \
+ -H "Content-Type: application/json" \
+ -d '{
+ "model": "a2a/my-agent",
+ "messages": [
+ {"role": "user", "content": "Hello, what can you do?"}
+ ]
+ }'
+```
+
+
+
+
+### Streaming
+
+
+
+
+```python showLineNumbers title="openai_streaming.py"
+import openai
+
+client = openai.OpenAI(
+ api_key="sk-1234", # Your LiteLLM Virtual Key
+ base_url="http://localhost:4000" # Your LiteLLM proxy URL
+)
+
+stream = client.chat.completions.create(
+ model="a2a/my-agent", # Use a2a/ prefix with your agent name
+ messages=[
+ {"role": "user", "content": "Tell me a long story"}
+ ],
+ stream=True
+)
+
+for chunk in stream:
+ if chunk.choices[0].delta.content:
+ print(chunk.choices[0].delta.content, end="", flush=True)
+```
+
+
+
+
+```typescript showLineNumbers title="openai_streaming.ts"
+import OpenAI from 'openai';
+
+const client = new OpenAI({
+ apiKey: 'sk-1234', // Your LiteLLM Virtual Key
+ baseURL: 'http://localhost:4000' // Your LiteLLM proxy URL
+});
+
+const stream = await client.chat.completions.create({
+ model: 'a2a/my-agent', // Use a2a/ prefix with your agent name
+ messages: [
+ { role: 'user', content: 'Tell me a long story' }
+ ],
+ stream: true
+});
+
+for await (const chunk of stream) {
+ const content = chunk.choices[0]?.delta?.content;
+ if (content) {
+ process.stdout.write(content);
+ }
+}
+```
+
+
+
+
+```bash showLineNumbers title="curl_streaming.sh"
+curl -X POST http://localhost:4000/v1/chat/completions \
+ -H "Authorization: Bearer sk-1234" \
+ -H "Content-Type: application/json" \
+ -d '{
+ "model": "a2a/my-agent",
+ "messages": [
+ {"role": "user", "content": "Tell me a long story"}
+ ],
+ "stream": true
+ }'
+```
+
+
+
+
+## Key Differences
+
+| Method | Use Case | Advantages |
+|--------|----------|------------|
+| **A2A SDK** | Native A2A protocol integration | • Full A2A protocol support • Access to task states and artifacts • Context management |
+| **OpenAI SDK** | Familiar OpenAI-style interface | • Drop-in replacement for OpenAI calls • Easier migration from LLM to agent workflows • Works with existing OpenAI tooling |
+
+:::tip Model Prefix
+
+When using the OpenAI SDK, always prefix your agent name with `a2a/` (e.g., `a2a/my-agent`) to route requests to the A2A agent instead of an LLM provider.
+
+:::
diff --git a/docs/my-website/docs/adding_provider/simple_guardrail_tutorial.md b/docs/my-website/docs/adding_provider/simple_guardrail_tutorial.md
index 9c654cd1560..884a7397bde 100644
--- a/docs/my-website/docs/adding_provider/simple_guardrail_tutorial.md
+++ b/docs/my-website/docs/adding_provider/simple_guardrail_tutorial.md
@@ -101,12 +101,11 @@ model_list:
- model_name: gpt-4
litellm_params:
model: gpt-4
- api_key: os.environ/OPENAI_API_KEY
+ api_key: os.environ/OPENAI_API_KEY
-litellm_settings:
- guardrails:
+guardrails:
- guardrail_name: my_guardrail
- litellm_params:
+ litellm_params:
guardrail: my_guardrail
mode: during_call
api_key: os.environ/MY_GUARDRAIL_API_KEY
diff --git a/docs/my-website/docs/benchmarks.md b/docs/my-website/docs/benchmarks.md
index 640212808bd..a1489081b4c 100644
--- a/docs/my-website/docs/benchmarks.md
+++ b/docs/my-website/docs/benchmarks.md
@@ -48,6 +48,28 @@ In these tests the baseline latency characteristics are measured against a fake-
- High-percentile latencies drop significantly: P95 630 ms → 150 ms, P99 1,200 ms → 240 ms.
- Setting workers equal to CPU count gives optimal performance.
+## `/realtime` API Benchmarks
+
+End-to-end latency benchmarks for the `/realtime` endpoint tested against a fake realtime endpoint.
+
+### Performance Metrics
+
+| Metric | Value |
+| --------------- | ---------- |
+| Median latency | 59 ms |
+| p95 latency | 67 ms |
+| p99 latency | 99 ms |
+| Average latency | 63 ms |
+| RPS | 1,207 |
+
+### Test Setup
+
+| Category | Specification |
+|----------|---------------|
+| **Load Testing** | Locust: 1,000 concurrent users, 500 ramp-up |
+| **System** | 4 vCPUs, 8 GB RAM, 4 workers, 4 instances |
+| **Database** | PostgreSQL (Redis unused) |
+
## Machine Spec used for testing
Each machine deploying LiteLLM had the following specs:
diff --git a/docs/my-website/docs/completion/web_search.md b/docs/my-website/docs/completion/web_search.md
index db50c7b5bc5..9ba66c730f0 100644
--- a/docs/my-website/docs/completion/web_search.md
+++ b/docs/my-website/docs/completion/web_search.md
@@ -18,12 +18,29 @@ Each provider uses their own search backend:
| Provider | Search Engine | Notes |
|----------|---------------|-------|
-| **OpenAI** (`gpt-4o-search-preview`) | OpenAI's internal search | Real-time web data |
+| **OpenAI** (`gpt-4o-search-preview`, `gpt-4o-mini-search-preview`, `gpt-5-search-api`) | OpenAI's internal search | Real-time web data |
| **xAI** (`grok-3`) | xAI's search + X/Twitter | Real-time social media data |
| **Google AI/Vertex** (`gemini-2.0-flash`) | **Google Search** | Uses actual Google search results |
| **Anthropic** (`claude-3-5-sonnet`) | Anthropic's web search | Real-time web data |
| **Perplexity** | Perplexity's search engine | AI-powered search and reasoning |
+:::warning Important: Only Search Models Support `web_search_options`
+For OpenAI, only dedicated search models support the `web_search_options` parameter:
+- `gpt-4o-search-preview`
+- `gpt-4o-mini-search-preview`
+- `gpt-5-search-api`
+
+**Regular models like `gpt-5`, `gpt-4.1`, `gpt-4o` do not support `web_search_options`**
+:::
+
+:::tip The `web_search_options` parameter is optional
+Search models (like `gpt-4o-search-preview`) **automatically search the web** even without the `web_search_options` parameter.
+
+Use `web_search_options` when you need to:
+- Adjust `search_context_size` (`"low"`, `"medium"`, `"high"`)
+- Specify `user_location` for localized results
+:::
+
:::info
**Anthropic Web Search Models**: Claude models that support web search: `claude-3-5-sonnet-latest`, `claude-3-5-sonnet-20241022`, `claude-3-5-haiku-latest`, `claude-3-5-haiku-20241022`, `claude-3-7-sonnet-20250219`
:::
diff --git a/docs/my-website/docs/enterprise.md b/docs/my-website/docs/enterprise.md
index 2eed0f53e59..0a1b47f0621 100644
--- a/docs/my-website/docs/enterprise.md
+++ b/docs/my-website/docs/enterprise.md
@@ -74,6 +74,18 @@ You can find [supported data regions litellm here](../docs/data_security#support
## Frequently Asked Questions
+### How to set up and verify your Enterprise License
+
+1. Add your license key to the environment:
+
+```env
+LITELLM_LICENSE="eyJ..."
+```
+
+2. Restart LiteLLM Proxy.
+
+3. Open `http://:/` — the Swagger page should show **"Enterprise Edition"** in the description. If it doesn't, check that the key is correct, unexpired, and that the proxy was fully restarted.
+
### SLA's + Professional Support
Professional Support can assist with LLM/Provider integrations, deployment, upgrade management, and LLM Provider troubleshooting. We can’t solve your own infrastructure-related issues but we will guide you to fix them.
diff --git a/docs/my-website/docs/mcp_public_internet.md b/docs/my-website/docs/mcp_public_internet.md
new file mode 100644
index 00000000000..69dd7464657
--- /dev/null
+++ b/docs/my-website/docs/mcp_public_internet.md
@@ -0,0 +1,251 @@
+import Tabs from '@theme/Tabs';
+import TabItem from '@theme/TabItem';
+
+# Exposing MCPs on the Public Internet
+
+Control which MCP servers are visible to external callers (e.g., ChatGPT, Claude Desktop) vs. internal-only callers. This is useful when you want a subset of your MCP servers available publicly while keeping sensitive servers restricted to your private network.
+
+## Overview
+
+| Property | Details |
+|-------|-------|
+| Description | IP-based access control for MCP servers — external callers only see servers marked as public |
+| Setting | `available_on_public_internet` on each MCP server |
+| Network Config | `mcp_internal_ip_ranges` in `general_settings` |
+| Supported Clients | ChatGPT, Claude Desktop, Cursor, OpenAI API, or any MCP client |
+
+## How It Works
+
+When a request arrives at LiteLLM's MCP endpoints, LiteLLM checks the caller's IP address to determine whether they are an **internal** or **external** caller:
+
+1. **Extract the client IP** from the incoming request (supports `X-Forwarded-For` when configured behind a reverse proxy).
+2. **Classify the IP** as internal or external by checking it against the configured private IP ranges (defaults to RFC 1918: `10.0.0.0/8`, `172.16.0.0/12`, `192.168.0.0/16`, `127.0.0.0/8`).
+3. **Filter the server list**:
+ - **Internal callers** see all MCP servers (public and private).
+ - **External callers** only see servers with `available_on_public_internet: true`.
+
+This filtering is applied at every MCP access point: the MCP registry, tool listing, tool calling, dynamic server routes, and OAuth discovery endpoints.
+
+```mermaid
+flowchart TD
+ A[Incoming MCP Request] --> B[Extract Client IP Address]
+ B --> C{Is IP in private ranges?}
+ C -->|Yes - Internal caller| D[Return ALL MCP servers]
+ C -->|No - External caller| E[Return ONLY servers with available_on_public_internet = true]
+```
+
+## Walkthrough
+
+This walkthrough covers two flows:
+1. **Adding a public MCP server** (DeepWiki) and connecting to it from ChatGPT
+2. **Making an existing server private** (Exa) and verifying ChatGPT no longer sees it
+
+### Flow 1: Add a Public MCP Server (DeepWiki)
+
+DeepWiki is a free MCP server — a good candidate to expose publicly so AI gateway users can access it from ChatGPT.
+
+#### Step 1: Create the MCP Server
+
+Navigate to the MCP Servers page and click **"+ Add New MCP Server"**.
+
+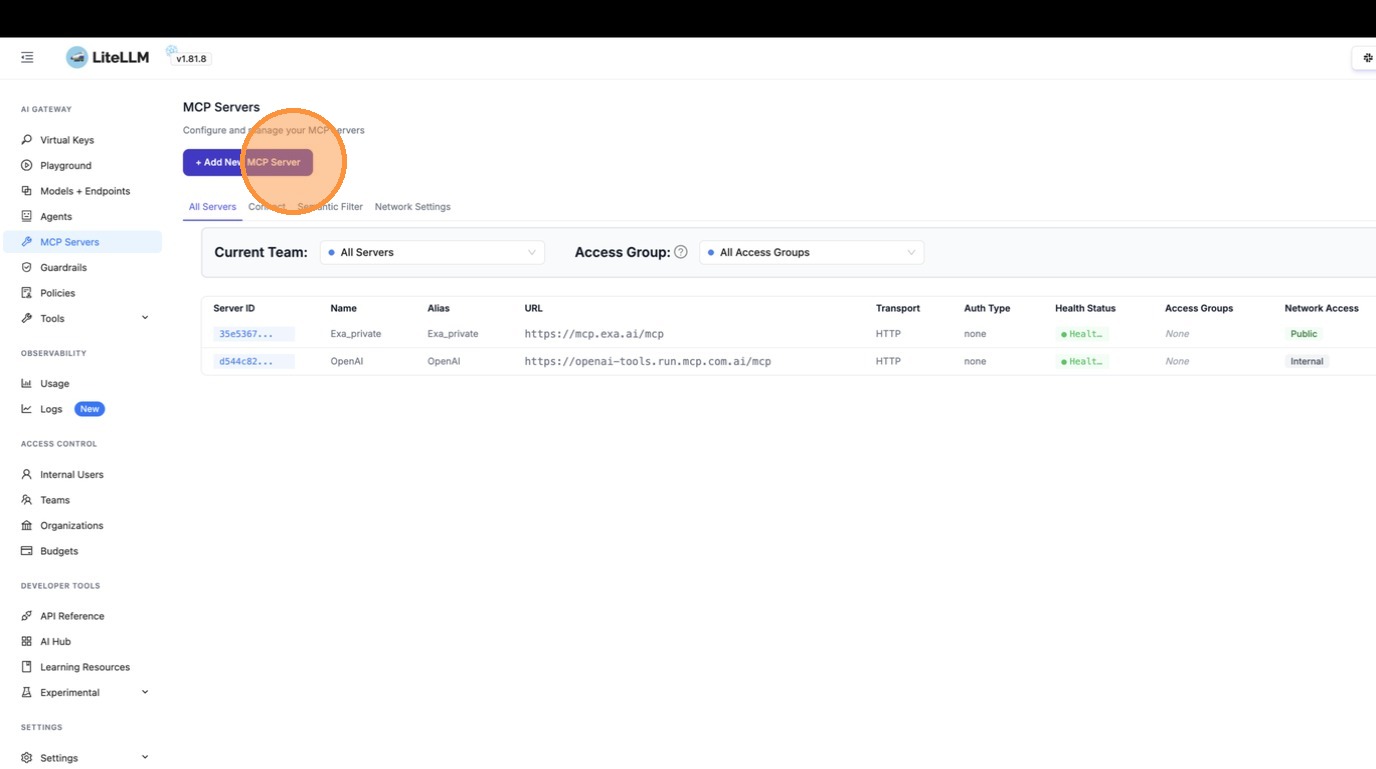
+
+The create dialog opens. Enter **"DeepWiki"** as the server name.
+
+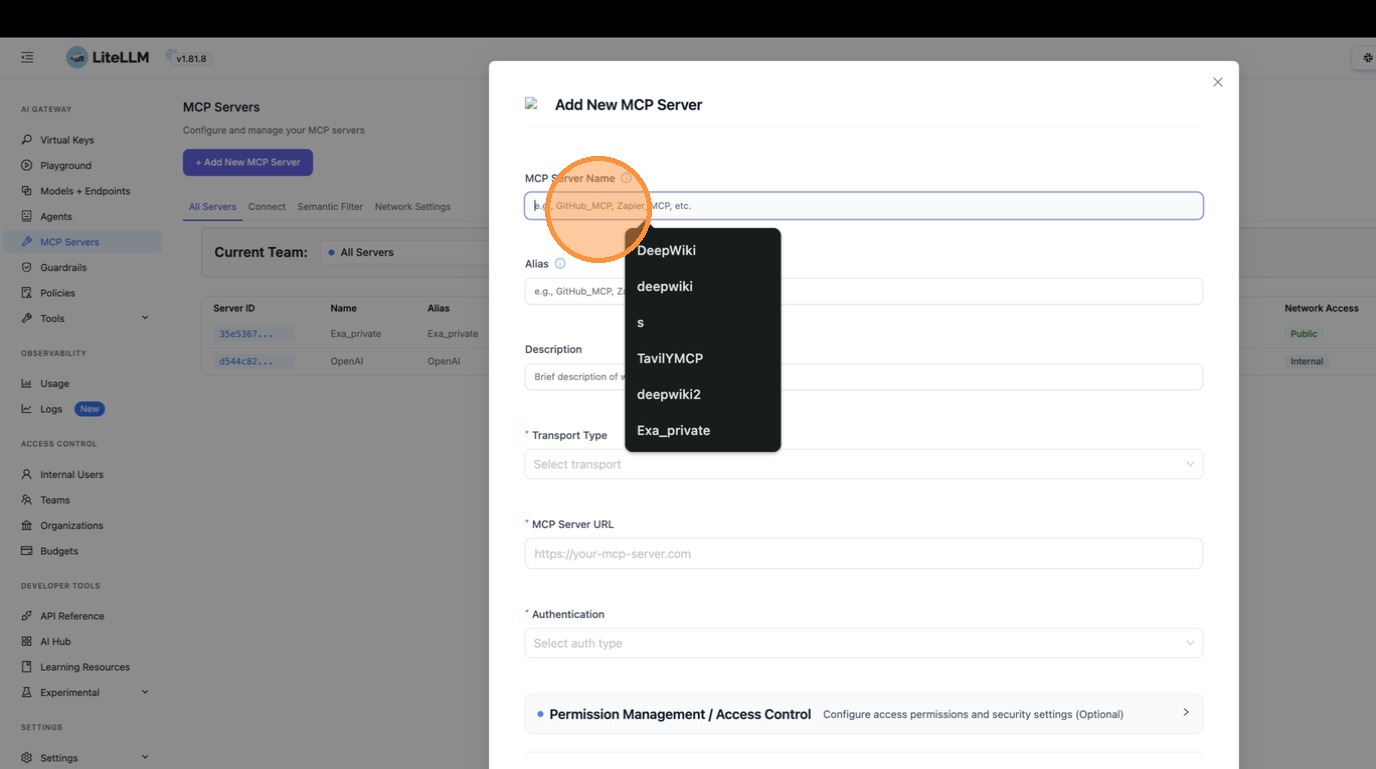
+
+For the transport type dropdown, select **HTTP** since DeepWiki uses the Streamable HTTP transport.
+
+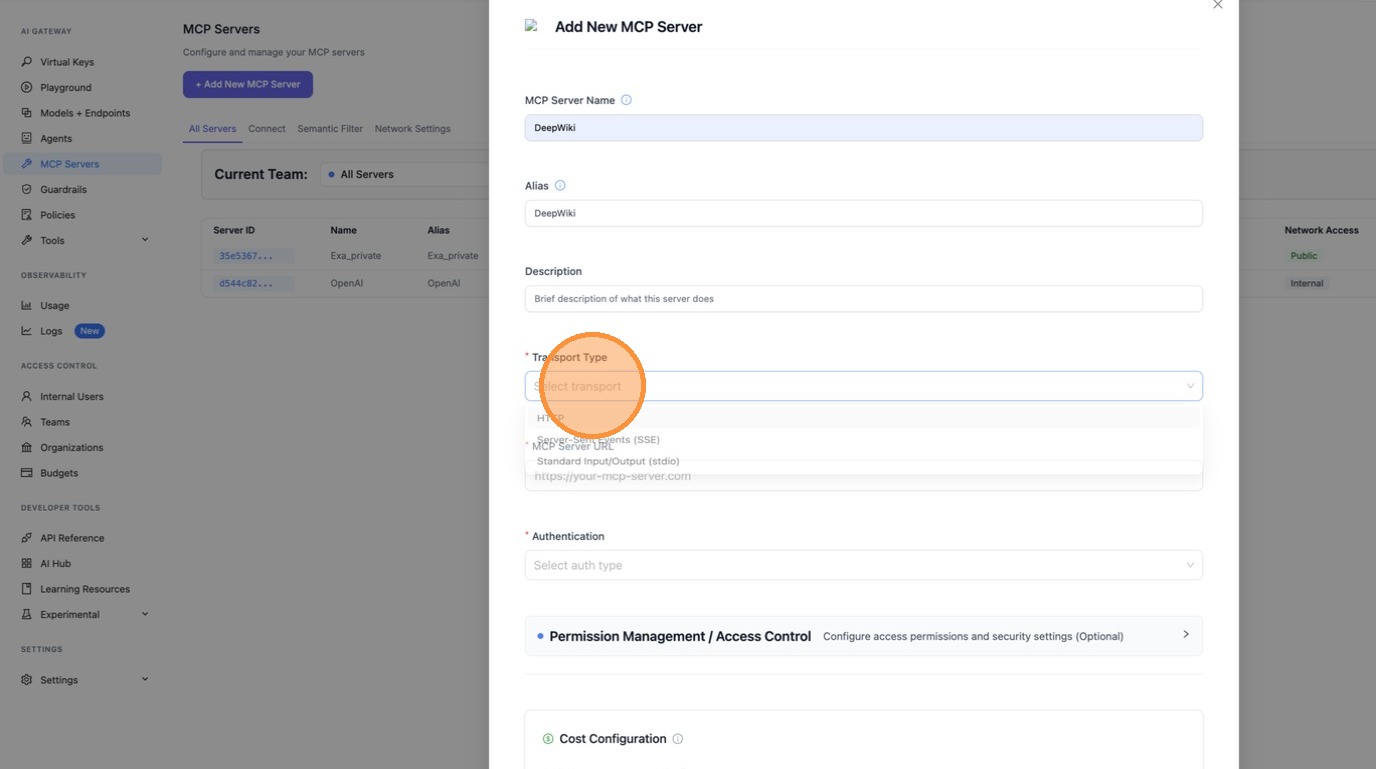
+
+Now scroll down to the MCP Server URL field.
+
+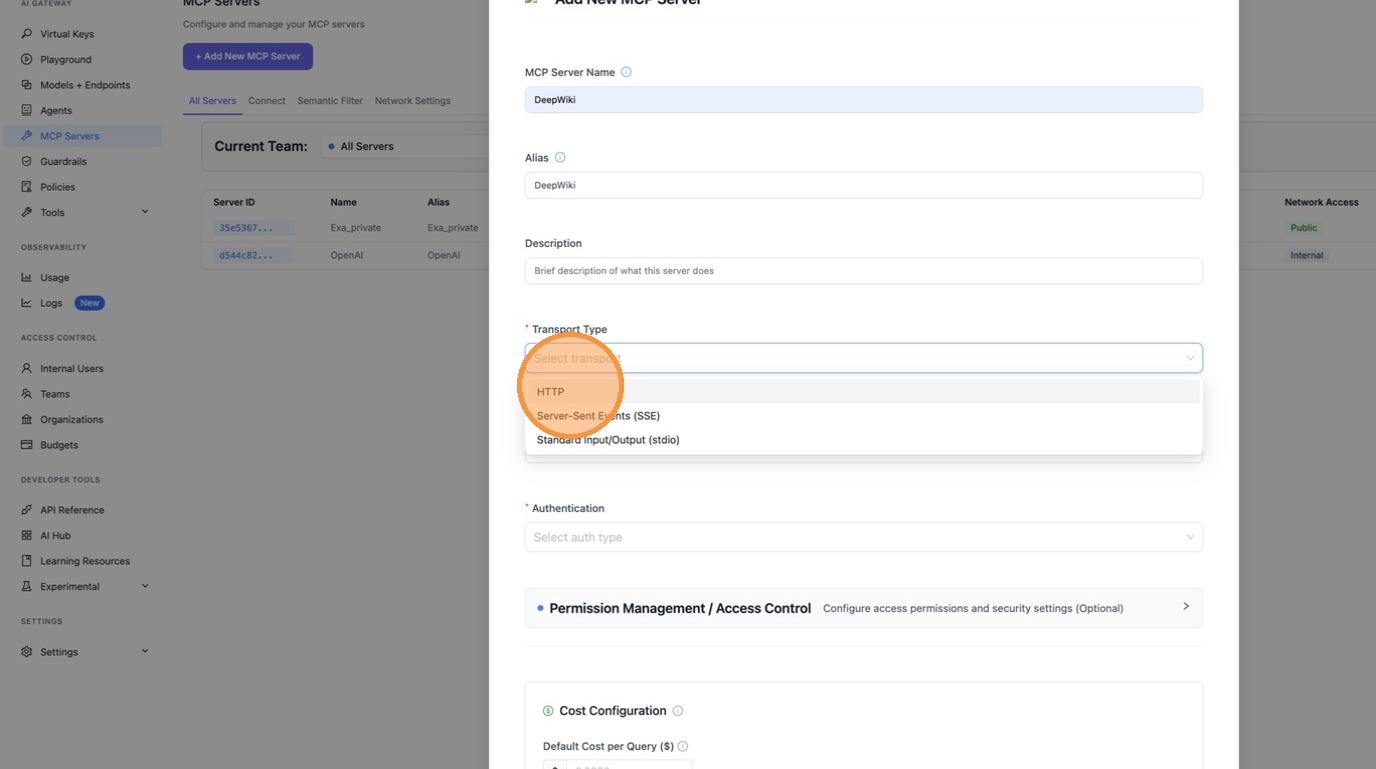
+
+Enter the DeepWiki MCP URL: `https://mcp.deepwiki.com/mcp`.
+
+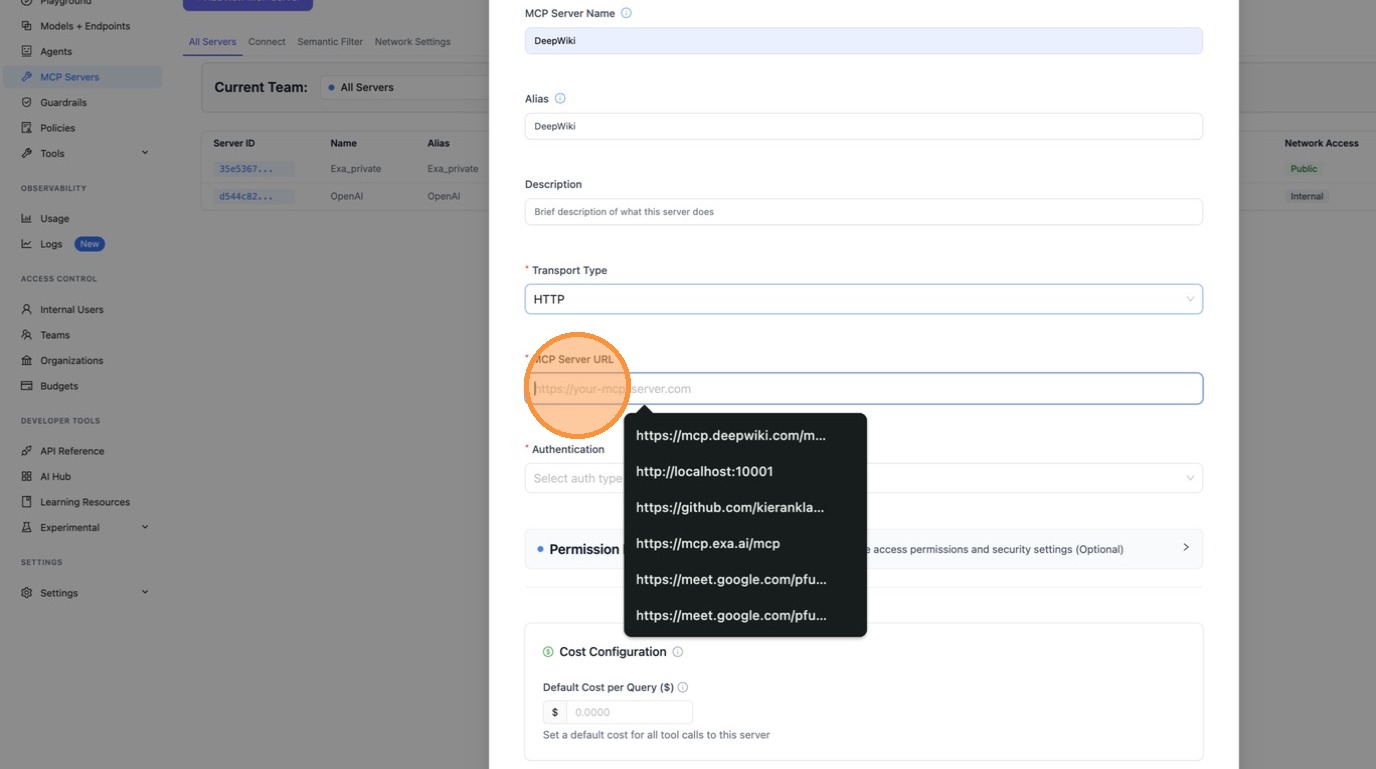
+
+With the name, transport, and URL filled in, the basic server configuration is complete.
+
+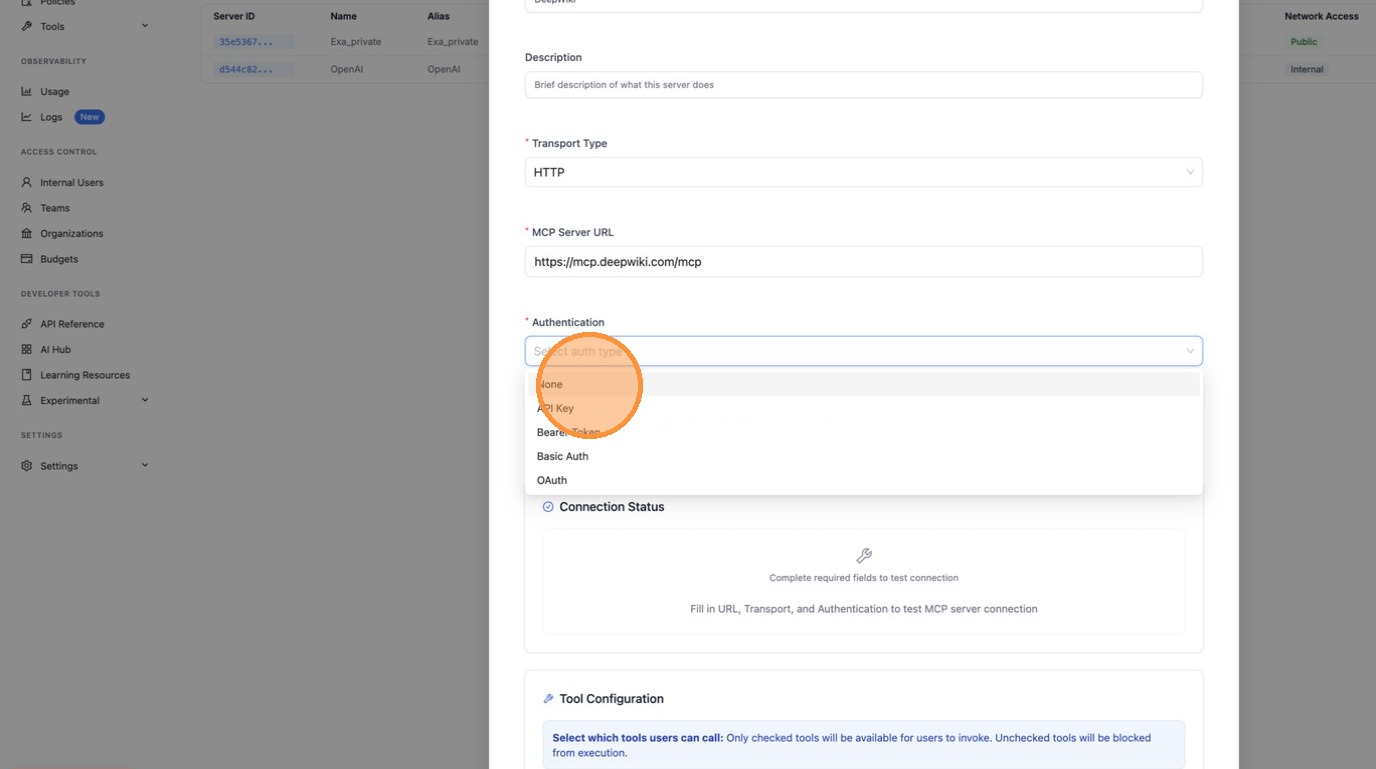
+
+#### Step 2: Enable "Available on Public Internet"
+
+Before creating, scroll down and expand the **Permission Management / Access Control** section. This is where you control who can see this server.
+
+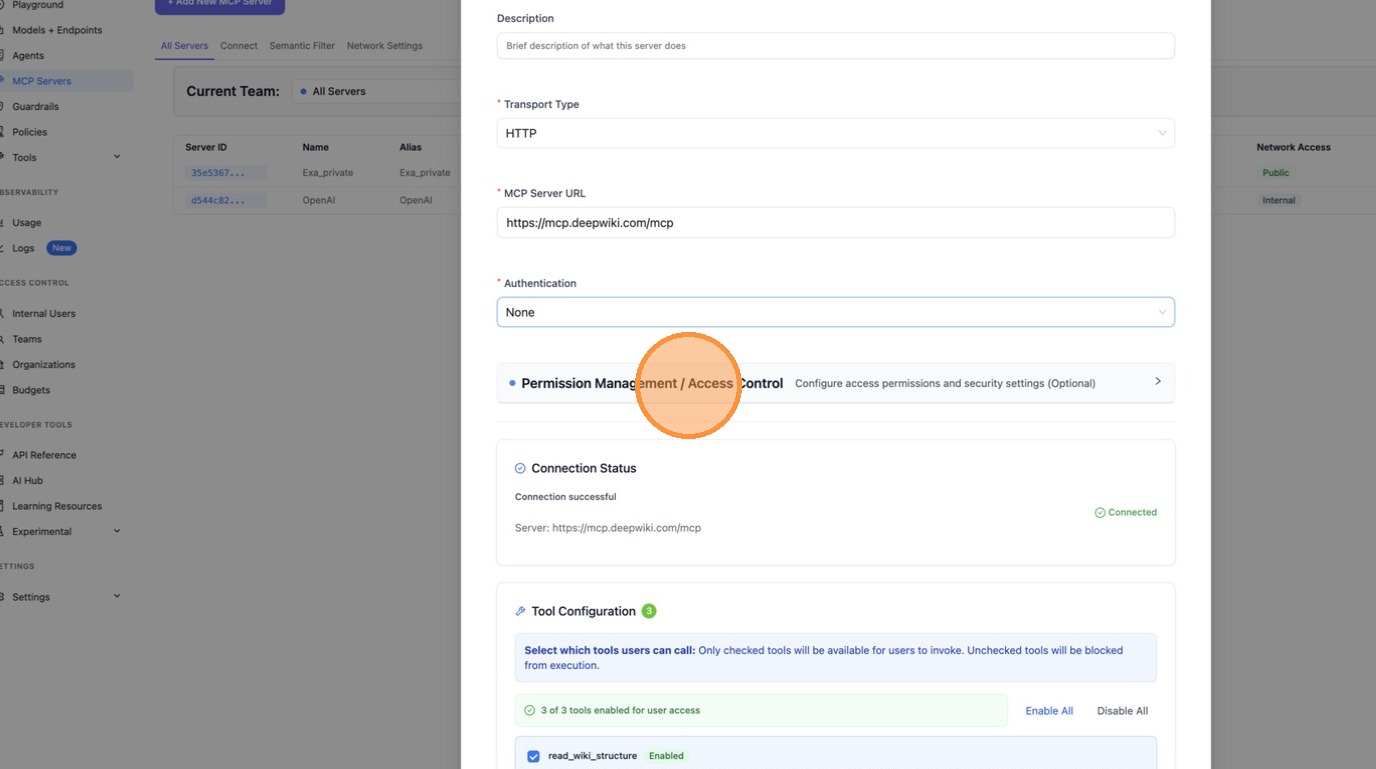
+
+Toggle **"Available on Public Internet"** on. This is the key setting — it tells LiteLLM that external callers (like ChatGPT connecting from the public internet) should be able to discover and use this server.
+
+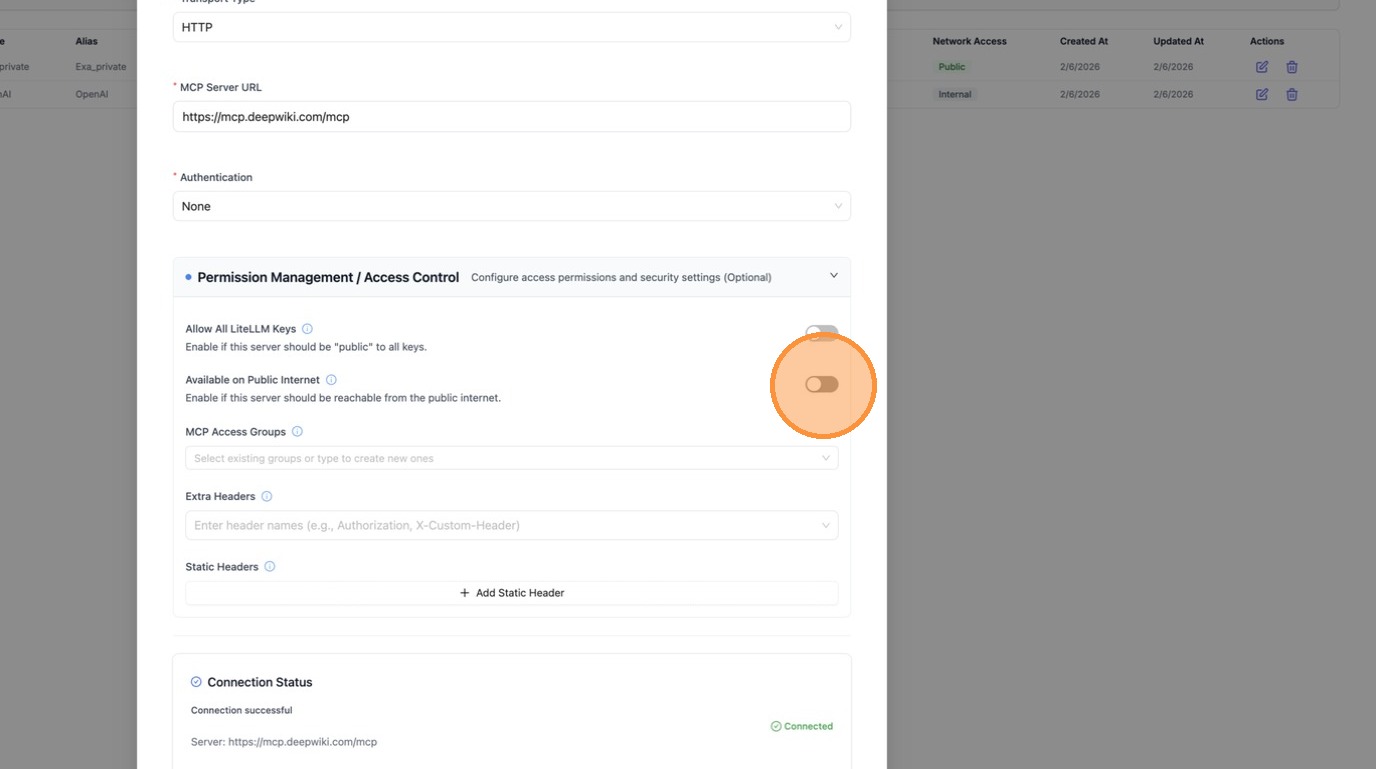
+
+With the toggle enabled, click **"Create"** to save the server.
+
+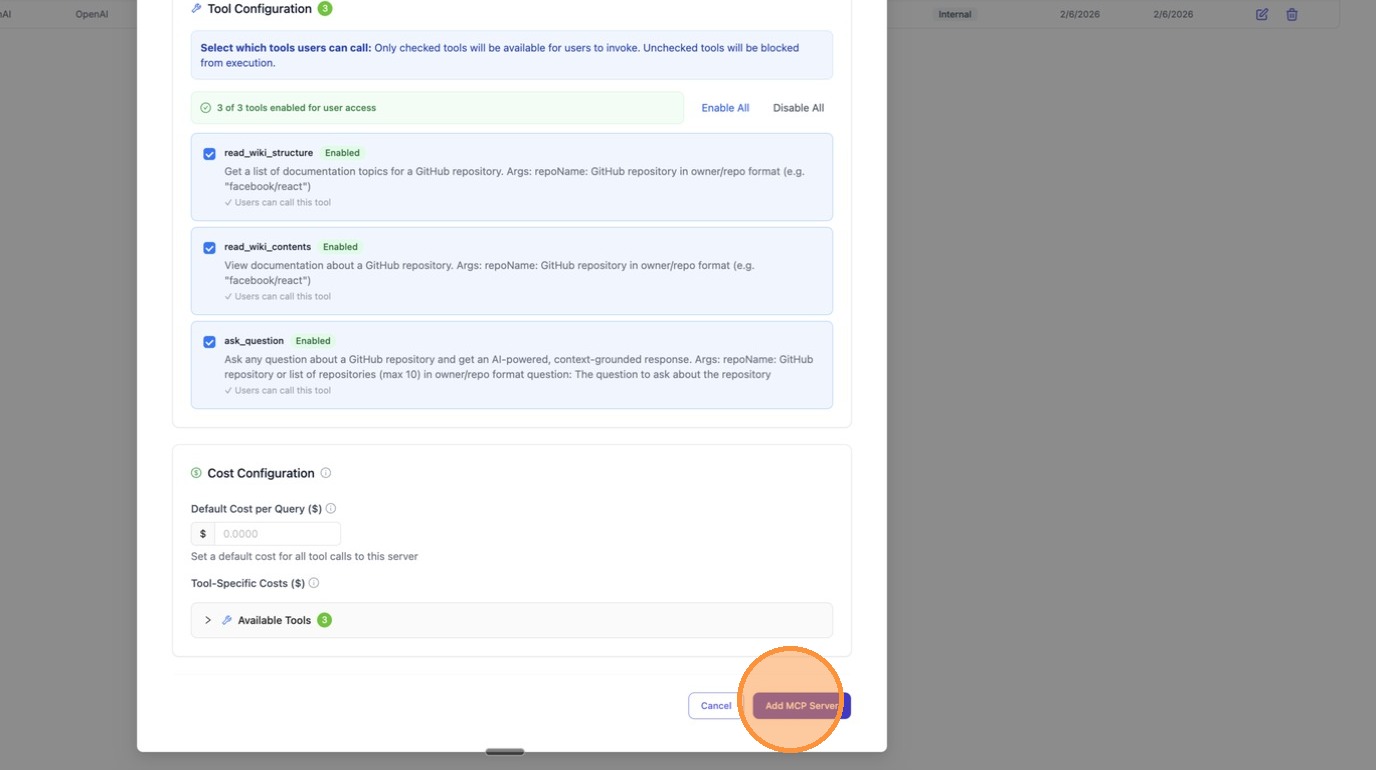
+
+#### Step 3: Connect from ChatGPT
+
+Now let's verify it works. Open ChatGPT and look for the MCP server icon to add a new connection. The endpoint to use is `/mcp`.
+
+
+
+In the dropdown, select **"Add an MCP server"** to configure a new connection.
+
+
+
+ChatGPT asks for a server label. Give it a recognizable name like "LiteLLM".
+
+
+
+Next, enter the Server URL. This should be your LiteLLM proxy's MCP endpoint — `/mcp`.
+
+
+
+Paste your LiteLLM URL and confirm it looks correct.
+
+
+
+ChatGPT also needs authentication. Enter your LiteLLM API key in the authentication field so it can connect to the proxy.
+
+
+
+Click **"Connect"** to establish the connection.
+
+
+
+ChatGPT connects and shows the available tools. Since both DeepWiki and Exa are currently marked as public, ChatGPT can see tools from both servers.
+
+
+
+---
+
+### Flow 2: Make an Existing Server Private (Exa)
+
+Now let's do the reverse — take an existing MCP server (Exa) that's currently public and restrict it to internal access only. After this change, ChatGPT should no longer see Exa's tools.
+
+#### Step 1: Edit the Server
+
+Go to the MCP Servers table and click on the Exa server to open its detail view.
+
+
+
+Switch to the **"Settings"** tab to access the edit form.
+
+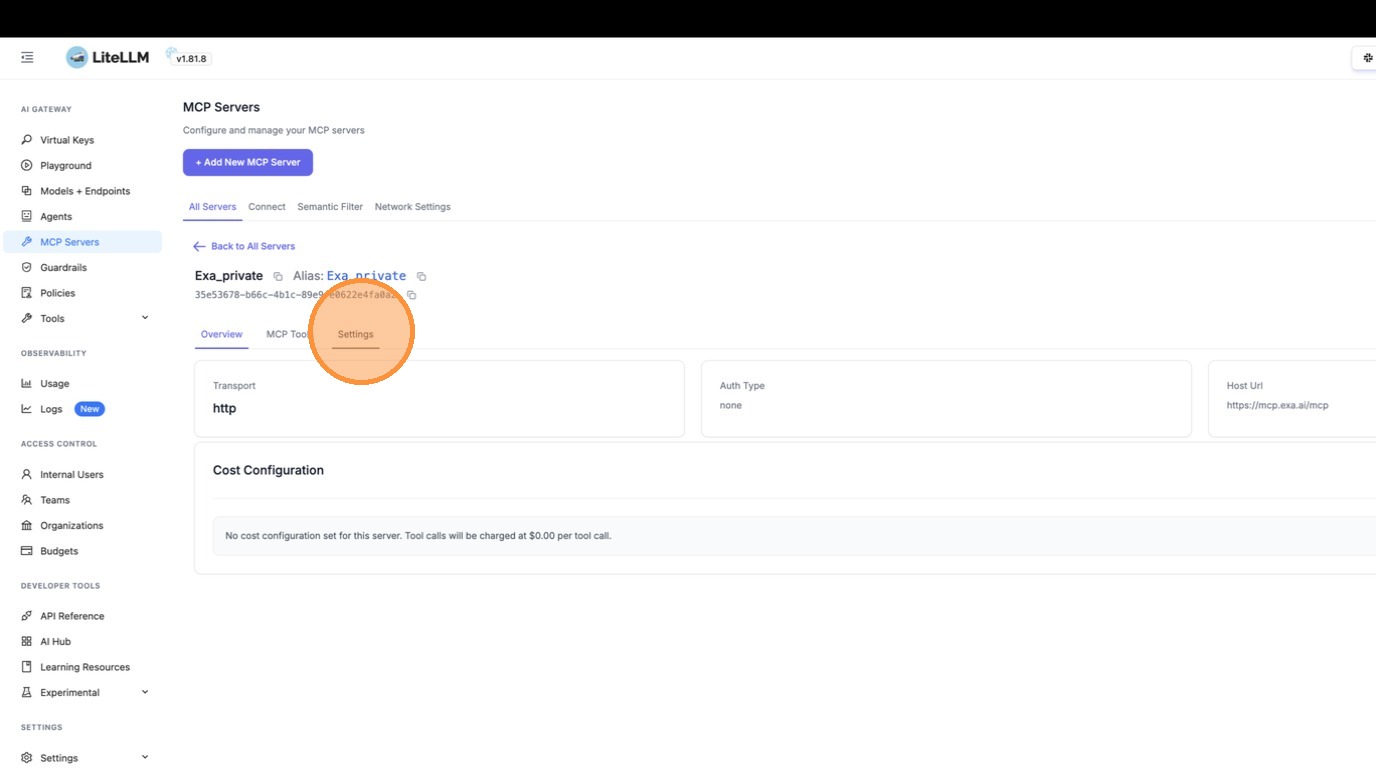
+
+The edit form loads with Exa's current configuration.
+
+
+
+#### Step 2: Toggle Off "Available on Public Internet"
+
+Scroll down and expand the **Permission Management / Access Control** section to find the public internet toggle.
+
+
+
+Toggle **"Available on Public Internet"** off. This will hide Exa from any caller outside your private network.
+
+
+
+Click **"Save Changes"** to apply. The change takes effect immediately — no proxy restart needed.
+
+
+
+#### Step 3: Verify in ChatGPT
+
+Go back to ChatGPT to confirm Exa is no longer visible. You'll need to reconnect for ChatGPT to re-fetch the tool list.
+
+
+
+Open the MCP server settings and select to add or reconnect a server.
+
+
+
+Enter the same LiteLLM MCP URL as before.
+
+
+
+Set the server label.
+
+
+
+Enter your API key for authentication.
+
+
+
+Click **"Connect"** to re-establish the connection.
+
+
+
+This time, only DeepWiki's tools appear — Exa is gone. LiteLLM detected that ChatGPT is calling from a public IP and filtered out Exa since it's no longer marked as public. Internal users on your private network would still see both servers.
+
+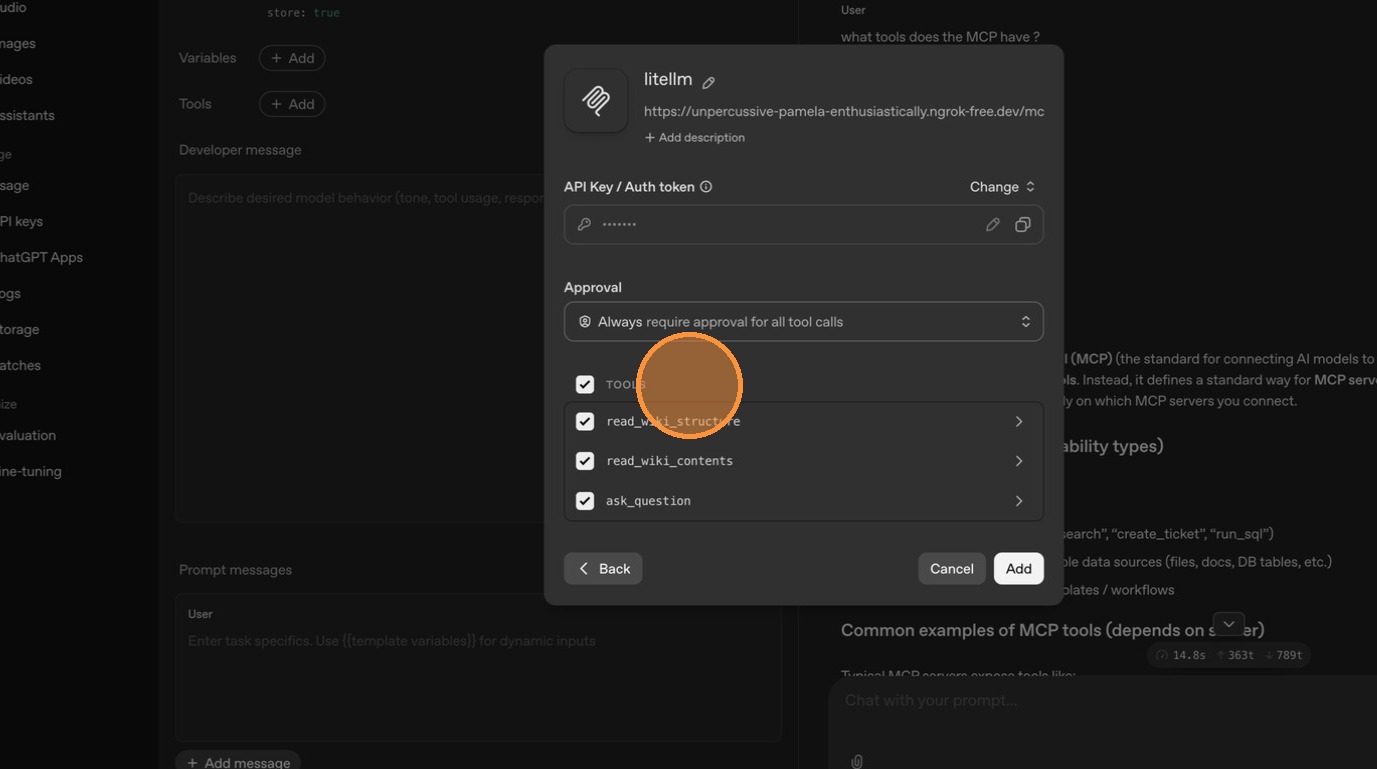
+
+## Configuration Reference
+
+### Per-Server Setting
+
+
+
+
+Toggle **"Available on Public Internet"** in the Permission Management section when creating or editing an MCP server.
+
+
+
+
+```yaml title="config.yaml" showLineNumbers
+mcp_servers:
+ deepwiki:
+ url: https://mcp.deepwiki.com/mcp
+ available_on_public_internet: true # visible to external callers
+
+ exa:
+ url: https://exa.ai/mcp
+ auth_type: api_key
+ auth_value: os.environ/EXA_API_KEY
+ available_on_public_internet: false # internal only (default)
+```
+
+
+
+
+```bash title="Create a public MCP server" showLineNumbers
+curl -X POST /v1/mcp/server \
+ -H "Authorization: Bearer sk-..." \
+ -H "Content-Type: application/json" \
+ -d '{
+ "server_name": "DeepWiki",
+ "url": "https://mcp.deepwiki.com/mcp",
+ "transport": "http",
+ "available_on_public_internet": true
+ }'
+```
+
+```bash title="Update an existing server" showLineNumbers
+curl -X PUT /v1/mcp/server \
+ -H "Authorization: Bearer sk-..." \
+ -H "Content-Type: application/json" \
+ -d '{
+ "server_id": "",
+ "available_on_public_internet": false
+ }'
+```
+
+
+
+
+### Custom Private IP Ranges
+
+By default, LiteLLM treats RFC 1918 private ranges as internal. You can customize this in the **Network Settings** tab under MCP Servers, or via config:
+
+```yaml title="config.yaml" showLineNumbers
+general_settings:
+ mcp_internal_ip_ranges:
+ - "10.0.0.0/8"
+ - "172.16.0.0/12"
+ - "192.168.0.0/16"
+ - "100.64.0.0/10" # Add your VPN/Tailscale range
+```
+
+When empty, the standard private ranges are used (`10.0.0.0/8`, `172.16.0.0/12`, `192.168.0.0/16`, `127.0.0.0/8`).
diff --git a/docs/my-website/docs/mcp_semantic_filter.md b/docs/my-website/docs/mcp_semantic_filter.md
new file mode 100644
index 00000000000..c58be80a680
--- /dev/null
+++ b/docs/my-website/docs/mcp_semantic_filter.md
@@ -0,0 +1,158 @@
+import Tabs from '@theme/Tabs';
+import TabItem from '@theme/TabItem';
+
+# MCP Semantic Tool Filter
+
+Automatically filter MCP tools by semantic relevance. When you have many MCP tools registered, LiteLLM semantically matches the user's query against tool descriptions and sends only the most relevant tools to the LLM.
+
+## How It Works
+
+Tool search shifts tool selection from a prompt-engineering problem to a retrieval problem. Instead of injecting a large static list of tools into every prompt, the semantic filter:
+
+1. Builds a semantic index of all available MCP tools on startup
+2. On each request, semantically matches the user's query against tool descriptions
+3. Returns only the top-K most relevant tools to the LLM
+
+This approach improves context efficiency, increases reliability by reducing tool confusion, and enables scalability to ecosystems with hundreds or thousands of MCP tools.
+
+```mermaid
+sequenceDiagram
+ participant Client
+ participant LiteLLM as LiteLLM Proxy
+ participant SemanticFilter as Semantic Filter
+ participant MCP as MCP Registry
+ participant LLM as LLM Provider
+
+ Note over LiteLLM,MCP: Startup: Build Semantic Index
+ LiteLLM->>MCP: Fetch all registered MCP tools
+ MCP->>LiteLLM: Return all tools (e.g., 50 tools)
+ LiteLLM->>SemanticFilter: Build semantic router with embeddings
+ SemanticFilter->>LLM: Generate embeddings for tool descriptions
+ LLM->>SemanticFilter: Return embeddings
+ Note over SemanticFilter: Index ready for fast lookup
+
+ Note over Client,LLM: Request: Semantic Tool Filtering
+ Client->>LiteLLM: POST /v1/responses with MCP tools
+ LiteLLM->>SemanticFilter: Expand MCP references (50 tools available)
+ SemanticFilter->>SemanticFilter: Extract user query from request
+ SemanticFilter->>LLM: Generate query embedding
+ LLM->>SemanticFilter: Return query embedding
+ SemanticFilter->>SemanticFilter: Match query against tool embeddings
+ SemanticFilter->>LiteLLM: Return top-K tools (e.g., 3 most relevant)
+ LiteLLM->>LLM: Forward request with filtered tools (3 tools)
+ LLM->>LiteLLM: Return response
+ LiteLLM->>Client: Response with headers x-litellm-semantic-filter: 50->3 x-litellm-semantic-filter-tools: tool1,tool2,tool3
+```
+
+## Configuration
+
+Enable semantic filtering in your LiteLLM config:
+
+```yaml title="config.yaml" showLineNumbers
+litellm_settings:
+ mcp_semantic_tool_filter:
+ enabled: true
+ embedding_model: "text-embedding-3-small" # Model for semantic matching
+ top_k: 5 # Max tools to return
+ similarity_threshold: 0.3 # Min similarity score
+```
+
+**Configuration Options:**
+- `enabled` - Enable/disable semantic filtering (default: `false`)
+- `embedding_model` - Model for generating embeddings (default: `"text-embedding-3-small"`)
+- `top_k` - Maximum number of tools to return (default: `10`)
+- `similarity_threshold` - Minimum similarity score for matches (default: `0.3`)
+
+## Usage
+
+Use MCP tools normally with the Responses API or Chat Completions. The semantic filter runs automatically:
+
+
+
+
+```bash title="Responses API with Semantic Filtering" showLineNumbers
+curl --location 'http://localhost:4000/v1/responses' \
+--header 'Content-Type: application/json' \
+--header "Authorization: Bearer sk-1234" \
+--data '{
+ "model": "gpt-4o",
+ "input": [
+ {
+ "role": "user",
+ "content": "give me TLDR of what BerriAI/litellm repo is about",
+ "type": "message"
+ }
+ ],
+ "tools": [
+ {
+ "type": "mcp",
+ "server_url": "litellm_proxy",
+ "require_approval": "never"
+ }
+ ],
+ "tool_choice": "required"
+}'
+```
+
+
+
+
+```bash title="Chat Completions with Semantic Filtering" showLineNumbers
+curl --location 'http://localhost:4000/v1/chat/completions' \
+--header 'Content-Type: application/json' \
+--header "Authorization: Bearer sk-1234" \
+--data '{
+ "model": "gpt-4o",
+ "messages": [
+ {"role": "user", "content": "Search Wikipedia for LiteLLM"}
+ ],
+ "tools": [
+ {
+ "type": "mcp",
+ "server_url": "litellm_proxy"
+ }
+ ]
+}'
+```
+
+
+
+
+## Response Headers
+
+The semantic filter adds diagnostic headers to every response:
+
+```
+x-litellm-semantic-filter: 10->3
+x-litellm-semantic-filter-tools: wikipedia-fetch,github-search,slack-post
+```
+
+- **`x-litellm-semantic-filter`** - Shows before→after tool count (e.g., `10->3` means 10 tools were filtered down to 3)
+- **`x-litellm-semantic-filter-tools`** - CSV list of the filtered tool names (max 150 chars, clipped with `...` if longer)
+
+These headers help you understand which tools were selected for each request and verify the filter is working correctly.
+
+## Example
+
+If you have 50 MCP tools registered and make a request asking about Wikipedia, the semantic filter will:
+
+1. Semantically match your query `"Search Wikipedia for LiteLLM"` against all 50 tool descriptions
+2. Select the top 5 most relevant tools (e.g., `wikipedia-fetch`, `wikipedia-search`, etc.)
+3. Pass only those 5 tools to the LLM
+4. Add headers showing `x-litellm-semantic-filter: 50->5`
+
+This dramatically reduces prompt size while ensuring the LLM has access to the right tools for the task.
+
+## Performance
+
+The semantic filter is optimized for production:
+- Router builds once on startup (no per-request overhead)
+- Semantic matching typically takes under 50ms
+- Fails gracefully - returns all tools if filtering fails
+- No impact on latency for requests without MCP tools
+
+## Related
+
+- [MCP Overview](./mcp.md) - Learn about MCP in LiteLLM
+- [MCP Permission Management](./mcp_control.md) - Control tool access by key/team
+- [Using MCP](./mcp_usage.md) - Complete MCP usage guide
diff --git a/docs/my-website/docs/observability/datadog.md b/docs/my-website/docs/observability/datadog.md
index 7cf91ced34c..6f785be1013 100644
--- a/docs/my-website/docs/observability/datadog.md
+++ b/docs/my-website/docs/observability/datadog.md
@@ -7,6 +7,7 @@ import TabItem from '@theme/TabItem';
LiteLLM Supports logging to the following Datdog Integrations:
- `datadog` [Datadog Logs](https://docs.datadoghq.com/logs/)
- `datadog_llm_observability` [Datadog LLM Observability](https://www.datadoghq.com/product/llm-observability/)
+- `datadog_cost_management` [Datadog Cloud Cost Management](#datadog-cloud-cost-management)
- `ddtrace-run` [Datadog Tracing](#datadog-tracing)
## Datadog Logs
@@ -73,7 +74,7 @@ Send logs through a local DataDog agent (useful for containerized environments):
```shell
LITELLM_DD_AGENT_HOST="localhost" # hostname or IP of DataDog agent
LITELLM_DD_AGENT_PORT="10518" # [OPTIONAL] port of DataDog agent (default: 10518)
-DD_API_KEY="5f2d0f310***********" # [OPTIONAL] your datadog API Key (agent handles auth)
+DD_API_KEY="5f2d0f310***********" # [OPTIONAL] your datadog API Key (Agent handles auth for Logs. REQUIRED for LLM Observability)
DD_SOURCE="litellm_dev" # [OPTIONAL] your datadog source
```
@@ -84,6 +85,9 @@ When `LITELLM_DD_AGENT_HOST` is set, logs are sent to the agent instead of direc
**Note:** We use `LITELLM_DD_AGENT_HOST` instead of `DD_AGENT_HOST` to avoid conflicts with `ddtrace` which automatically sets `DD_AGENT_HOST` for APM tracing.
+> [!IMPORTANT]
+> **Datadog LLM Observability**: `DD_API_KEY` is **REQUIRED** even when using the Datadog Agent (`LITELLM_DD_AGENT_HOST`). The agent acts as a proxy but the API key header is mandatory for the LLM Observability endpoint.
+
**Step 3**: Start the proxy, make a test request
Start proxy
@@ -161,6 +165,50 @@ On the Datadog LLM Observability page, you should see that both input messages a
+
+
+
+## Datadog Cloud Cost Management
+
+| Feature | Details |
+|---------|---------|
+| **What is logged** | Aggregated LLM Costs (FOCUS format) |
+| **Events** | Periodic Uploads of Aggregated Cost Data |
+| **Product Link** | [Datadog Cloud Cost Management](https://docs.datadoghq.com/cost_management/) |
+
+We will use the `--config` to set `litellm.callbacks = ["datadog_cost_management"]`. This will periodically upload aggregated LLM cost data to Datadog.
+
+**Step 1**: Create a `config.yaml` file and set `litellm_settings`: `success_callback`
+
+```yaml
+model_list:
+ - model_name: gpt-3.5-turbo
+ litellm_params:
+ model: gpt-3.5-turbo
+litellm_settings:
+ callbacks: ["datadog_cost_management"]
+```
+
+**Step 2**: Set Required env variables
+
+```shell
+DD_API_KEY="your-api-key"
+DD_APP_KEY="your-app-key" # REQUIRED for Cost Management
+DD_SITE="us5.datadoghq.com"
+```
+
+**Step 3**: Start the proxy
+
+```shell
+litellm --config config.yaml
+```
+
+**How it works**
+* LiteLLM aggregates costs in-memory by Provider, Model, Date, and Tags.
+* Requires `DD_APP_KEY` for the Custom Costs API.
+* Costs are uploaded periodically (flushed).
+
+
### Datadog Tracing
Use `ddtrace-run` to enable [Datadog Tracing](https://ddtrace.readthedocs.io/en/stable/installation_quickstart.html) on litellm proxy
@@ -203,5 +251,5 @@ LiteLLM supports customizing the following Datadog environment variables
| `POD_NAME` | Pod name tag (useful for Kubernetes deployments) | "unknown" | ❌ No |
\* **Required when using Direct API** (default): `DD_API_KEY` and `DD_SITE` are required
-\* **Optional when using DataDog Agent**: Set `LITELLM_DD_AGENT_HOST` to use agent mode; `DD_API_KEY` and `DD_SITE` are not required
+\* **Optional when using DataDog Agent**: Set `LITELLM_DD_AGENT_HOST` to use agent mode; `DD_API_KEY` and `DD_SITE` are not required for **Datadog Logs**. (**Note: `DD_API_KEY` IS REQUIRED for Datadog LLM Observability**)
diff --git a/docs/my-website/docs/observability/langfuse_integration.md b/docs/my-website/docs/observability/langfuse_integration.md
index a81336c5bc6..d3c5a44d481 100644
--- a/docs/my-website/docs/observability/langfuse_integration.md
+++ b/docs/my-website/docs/observability/langfuse_integration.md
@@ -215,6 +215,66 @@ The following parameters can be updated on a continuation of a trace by passing
Any other key value pairs passed into the metadata not listed in the above spec for a `litellm` completion will be added as a metadata key value pair for the generation.
+#### Multiple Langfuse Projects (Per-Request Credentials)
+
+You can send traces to different Langfuse projects per request by passing credentials directly to `completion()` or `acompletion()`. This works alongside (or instead of) the global env vars and is useful when different teams or business processes use different Langfuse projects.
+
+Pass **`langfuse_public_key`**, **`langfuse_secret_key`** (or **`langfuse_secret`**), and optionally **`langfuse_host`** as keyword arguments:
+
+```python
+import litellm
+from litellm import completion
+
+# Optional: set a default via env for requests that don't pass credentials
+# os.environ["LANGFUSE_PUBLIC_KEY"] = "pk-default..."
+# os.environ["LANGFUSE_SECRET_KEY"] = "sk-default..."
+
+litellm.success_callback = ["langfuse"]
+litellm.failure_callback = ["langfuse"]
+
+# Request 1 → Langfuse Project A
+response_a = completion(
+ model="gpt-3.5-turbo",
+ messages=[{"role": "user", "content": "Hello from team A"}],
+ langfuse_public_key="pk-lf-project-a...",
+ langfuse_secret_key="sk-lf-project-a...",
+ langfuse_host="https://us.cloud.langfuse.com", # optional
+)
+
+# Request 2 → Langfuse Project B (different project)
+response_b = completion(
+ model="gpt-3.5-turbo",
+ messages=[{"role": "user", "content": "Hello from team B"}],
+ langfuse_public_key="pk-lf-project-b...",
+ langfuse_secret_key="sk-lf-project-b...",
+ langfuse_host="https://eu.cloud.langfuse.com", # optional, can differ per project
+)
+```
+
+Async usage with per-request credentials:
+
+```python
+import litellm
+from litellm import acompletion
+
+litellm.success_callback = ["langfuse"]
+litellm.failure_callback = ["langfuse"]
+
+response = await acompletion(
+ model="gpt-3.5-turbo",
+ messages=[{"role": "user", "content": "Hi"}],
+ langfuse_public_key="pk-lf-...",
+ langfuse_secret_key="sk-lf-...",
+ langfuse_host="https://us.cloud.langfuse.com", # optional
+)
+```
+
+- **`langfuse_public_key`** – Langfuse project public key (required for per-request override).
+- **`langfuse_secret_key`** or **`langfuse_secret`** – Langfuse secret key (either name is accepted).
+- **`langfuse_host`** – Langfuse host URL (e.g. `https://us.cloud.langfuse.com`); optional, defaults to env or Langfuse cloud.
+
+When these are passed, that request uses this project (and host) for the Langfuse callback; when omitted, the callback uses the global Langfuse client (from env vars if set). LiteLLM caches a Langfuse client per credential set to avoid creating a new client on every request.
+
#### Disable Logging - Specific Calls
To disable logging for specific calls use the `no-log` flag.
diff --git a/docs/my-website/docs/pass_through/openai_passthrough.md b/docs/my-website/docs/pass_through/openai_passthrough.md
index d7c98eba7b3..49026f8aa2d 100644
--- a/docs/my-website/docs/pass_through/openai_passthrough.md
+++ b/docs/my-website/docs/pass_through/openai_passthrough.md
@@ -1,6 +1,6 @@
# OpenAI Passthrough
-Pass-through endpoints for `/openai`
+Pass-through endpoints for direct OpenAI API access
## Overview
@@ -10,12 +10,27 @@ Pass-through endpoints for `/openai`
| Logging | ✅ | Works across all integrations |
| Streaming | ✅ | Fully supported |
-### When to use this?
+## Available Endpoints
+
+### `/openai_passthrough` - Recommended
+Dedicated passthrough endpoint that guarantees direct routing to OpenAI without conflicts.
+
+**Use this for:**
+- OpenAI Responses API (`/v1/responses`)
+- Any endpoint where you need guaranteed passthrough
+- When `/openai` routes are conflicting with LiteLLM's native implementations
+
+### `/openai` - Legacy
+Standard passthrough endpoint that may conflict with LiteLLM's native implementations.
+
+**Note:** Some endpoints like `/openai/v1/responses` will be routed to LiteLLM's native implementation instead of OpenAI.
+
+## When to use this?
- For 90% of your use cases, you should use the [native LiteLLM OpenAI Integration](https://docs.litellm.ai/docs/providers/openai) (`/chat/completions`, `/embeddings`, `/completions`, `/images`, `/batches`, etc.)
-- Use this passthrough to call less popular or newer OpenAI endpoints that LiteLLM doesn't fully support yet, such as `/assistants`, `/threads`, `/vector_stores`
+- Use `/openai_passthrough` to call less popular or newer OpenAI endpoints that LiteLLM doesn't fully support yet, such as `/assistants`, `/threads`, `/vector_stores`, `/responses`
-Simply replace `https://api.openai.com` with `LITELLM_PROXY_BASE_URL/openai`
+Simply replace `https://api.openai.com` with `LITELLM_PROXY_BASE_URL/openai_passthrough`
## Usage Examples
@@ -34,7 +49,7 @@ Make sure you do the following:
import openai
client = openai.OpenAI(
- base_url="http://0.0.0.0:4000/openai", # /openai
+ base_url="http://0.0.0.0:4000/openai_passthrough", # /openai_passthrough
api_key="sk-anything" #
)
```
diff --git a/docs/my-website/docs/providers/anthropic_tool_search.md b/docs/my-website/docs/providers/anthropic_tool_search.md
index 28ce5688eeb..203a2947ebc 100644
--- a/docs/my-website/docs/providers/anthropic_tool_search.md
+++ b/docs/my-website/docs/providers/anthropic_tool_search.md
@@ -1,43 +1,46 @@
-# Anthropic Tool Search
+# Tool Search
Tool search enables Claude to dynamically discover and load tools on-demand from large tool catalogs (10,000+ tools). Instead of loading all tool definitions into the context window upfront, Claude searches your tool catalog and loads only the tools it needs.
+## Supported Providers
+
+| Provider | Chat Completions API | Messages API |
+|----------|---------------------|--------------|
+| **Anthropic API** | ✅ | ✅ |
+| **Azure Anthropic** (Microsoft Foundry) | ✅ | ✅ |
+| **Google Cloud Vertex AI** | ✅ | ✅ |
+| **Amazon Bedrock** | ✅ (Invoke API only, Opus 4.5 only) | ✅ (Invoke API only, Opus 4.5 only) |
+
+
## Benefits
- **Context efficiency**: Avoid consuming massive portions of your context window with tool definitions
- **Better tool selection**: Claude's tool selection accuracy degrades with more than 30-50 tools. Tool search maintains accuracy even with thousands of tools
- **On-demand loading**: Tools are only loaded when Claude needs them
-## Supported Models
-
-Tool search is available on:
-- Claude Opus 4.5
-- Claude Sonnet 4.5
-
-## Supported Platforms
-
-- Anthropic API (direct)
-- Azure Anthropic (Microsoft Foundry)
-- Google Cloud Vertex AI
-- Amazon Bedrock (invoke API only, not converse API)
-
## Tool Search Variants
LiteLLM supports both tool search variants:
### 1. Regex Tool Search (`tool_search_tool_regex_20251119`)
-Claude constructs regex patterns to search for tools.
+Claude constructs regex patterns to search for tools. Best for exact pattern matching (faster).
### 2. BM25 Tool Search (`tool_search_tool_bm25_20251119`)
-Claude uses natural language queries to search for tools using the BM25 algorithm.
+Claude uses natural language queries to search for tools using the BM25 algorithm. Best for natural language semantic search.
-## Quick Start
+**Note**: BM25 variant is not supported on Bedrock.
-### Basic Example with Regex Tool Search
+---
-```python
+## Chat Completions API
+
+### SDK Usage
+
+#### Basic Example with Regex Tool Search
+
+```python showLineNumbers title="Basic Tool Search Example"
import litellm
response = litellm.completion(
@@ -70,26 +73,6 @@ response = litellm.completion(
}
},
"defer_loading": True # Mark for deferred loading
- },
- # Another deferred tool
- {
- "type": "function",
- "function": {
- "name": "search_files",
- "description": "Search through files in the workspace",
- "parameters": {
- "type": "object",
- "properties": {
- "query": {"type": "string"},
- "file_types": {
- "type": "array",
- "items": {"type": "string"}
- }
- },
- "required": ["query"]
- }
- },
- "defer_loading": True
}
]
)
@@ -97,9 +80,9 @@ response = litellm.completion(
print(response.choices[0].message.content)
```
-### BM25 Tool Search Example
+#### BM25 Tool Search Example
-```python
+```python showLineNumbers title="BM25 Tool Search"
import litellm
response = litellm.completion(
@@ -134,9 +117,9 @@ response = litellm.completion(
)
```
-## Using with Azure Anthropic
+#### Azure Anthropic Example
-```python
+```python showLineNumbers title="Azure Anthropic Tool Search"
import litellm
response = litellm.completion(
@@ -170,9 +153,9 @@ response = litellm.completion(
)
```
-## Using with Vertex AI
+#### Vertex AI Example
-```python
+```python showLineNumbers title="Vertex AI Tool Search"
import litellm
response = litellm.completion(
@@ -192,11 +175,9 @@ response = litellm.completion(
)
```
-## Streaming Support
+#### Streaming Support
-Tool search works with streaming:
-
-```python
+```python showLineNumbers title="Streaming with Tool Search"
import litellm
response = litellm.completion(
@@ -233,13 +214,13 @@ for chunk in response:
print(chunk.choices[0].delta.content, end="")
```
-## LiteLLM Proxy
+### AI Gateway Usage
-Tool search works automatically through the LiteLLM proxy:
+Tool search works automatically through the LiteLLM proxy.
-### Proxy Config
+#### Proxy Configuration
-```yaml
+```yaml showLineNumbers title="config.yaml"
model_list:
- model_name: claude-sonnet
litellm_params:
@@ -247,18 +228,19 @@ model_list:
api_key: os.environ/ANTHROPIC_API_KEY
```
-### Client Request
+#### Client Request
-```python
-import openai
+```python showLineNumbers title="Client Request via Proxy"
+from anthropic import Anthropic
-client = openai.OpenAI(
+client = Anthropic(
api_key="your-litellm-proxy-key",
base_url="http://0.0.0.0:4000"
)
-response = client.chat.completions.create(
+response = client.messages.create(
model="claude-sonnet",
+ max_tokens=1024,
messages=[
{"role": "user", "content": "What's the weather?"}
],
@@ -268,17 +250,14 @@ response = client.chat.completions.create(
"name": "tool_search_tool_regex"
},
{
- "type": "function",
- "function": {
- "name": "get_weather",
- "description": "Get weather information",
- "parameters": {
- "type": "object",
- "properties": {
- "location": {"type": "string"}
- },
- "required": ["location"]
- }
+ "name": "get_weather",
+ "description": "Get weather information",
+ "input_schema": {
+ "type": "object",
+ "properties": {
+ "location": {"type": "string"}
+ },
+ "required": ["location"]
},
"defer_loading": True
}
@@ -286,127 +265,278 @@ response = client.chat.completions.create(
)
```
-## Important Notes
+---
-### Beta Header
+## Messages API
-LiteLLM automatically detects tool search tools and adds the appropriate beta header based on your provider:
+The Messages API provides native Anthropic-style tool search support via the `litellm.anthropic.messages` interface.
-- **Anthropic API & Microsoft Foundry**: `advanced-tool-use-2025-11-20`
-- **Google Cloud Vertex AI**: `tool-search-tool-2025-10-19`
-- **Amazon Bedrock** (Invoke API, Opus 4.5 only): `tool-search-tool-2025-10-19`
+### SDK Usage
-You don't need to manually specify beta headers—LiteLLM handles this automatically.
+#### Basic Example
-### Deferred Loading
+```python showLineNumbers title="Messages API - Basic Tool Search"
+import litellm
-- Tools with `defer_loading: true` are only loaded when Claude discovers them via search
-- At least one tool must be non-deferred (the tool search tool itself)
-- Keep your 3-5 most frequently used tools as non-deferred for optimal performance
-
-### Tool Descriptions
-
-Write clear, descriptive tool names and descriptions that match how users describe tasks. The search algorithm uses:
-- Tool names
-- Tool descriptions
-- Argument names
-- Argument descriptions
-
-### Usage Tracking
-
-Tool search requests are tracked in the usage object:
-
-```python
-response = litellm.completion(
- model="anthropic/claude-sonnet-4-5-20250929",
- messages=[{"role": "user", "content": "Search for tools"}],
- tools=[...]
+response = await litellm.anthropic.messages.acreate(
+ model="anthropic/claude-sonnet-4-20250514",
+ messages=[
+ {
+ "role": "user",
+ "content": "What's the weather in San Francisco?"
+ }
+ ],
+ tools=[
+ {
+ "type": "tool_search_tool_regex_20251119",
+ "name": "tool_search_tool_regex"
+ },
+ {
+ "name": "get_weather",
+ "description": "Get the current weather for a location",
+ "input_schema": {
+ "type": "object",
+ "properties": {
+ "location": {
+ "type": "string",
+ "description": "The city and state, e.g. San Francisco, CA"
+ }
+ },
+ "required": ["location"]
+ },
+ "defer_loading": True
+ }
+ ],
+ max_tokens=1024,
+ extra_headers={"anthropic-beta": "advanced-tool-use-2025-11-20"}
)
-# Check tool search usage
-if response.usage.server_tool_use:
- print(f"Tool search requests: {response.usage.server_tool_use.tool_search_requests}")
+print(response)
```
-## Error Handling
+#### Azure Anthropic Messages Example
-### All Tools Deferred
+```python showLineNumbers title="Azure Anthropic Messages API"
+import litellm
-```python
-# ❌ This will fail - at least one tool must be non-deferred
-tools = [
- {
- "type": "function",
- "function": {...},
- "defer_loading": True
- }
-]
-
-# ✅ Correct - tool search tool is non-deferred
-tools = [
- {
- "type": "tool_search_tool_regex_20251119",
- "name": "tool_search_tool_regex"
- },
- {
- "type": "function",
- "function": {...},
- "defer_loading": True
- }
-]
+response = await litellm.anthropic.messages.acreate(
+ model="azure_anthropic/claude-sonnet-4-20250514",
+ messages=[
+ {
+ "role": "user",
+ "content": "What's the stock price of Apple?"
+ }
+ ],
+ tools=[
+ {
+ "type": "tool_search_tool_regex_20251119",
+ "name": "tool_search_tool_regex"
+ },
+ {
+ "name": "get_stock_price",
+ "description": "Get the current stock price for a ticker symbol",
+ "input_schema": {
+ "type": "object",
+ "properties": {
+ "ticker": {
+ "type": "string",
+ "description": "The stock ticker symbol, e.g. AAPL"
+ }
+ },
+ "required": ["ticker"]
+ },
+ "defer_loading": True
+ }
+ ],
+ max_tokens=1024,
+ extra_headers={"anthropic-beta": "advanced-tool-use-2025-11-20"}
+)
```
-### Missing Tool Definition
+#### Vertex AI Messages Example
-If Claude references a tool that isn't in your deferred tools list, you'll get an error. Make sure all tools that might be discovered are included in the tools parameter with `defer_loading: true`.
+```python showLineNumbers title="Vertex AI Messages API"
+import litellm
-## Best Practices
+response = await litellm.anthropic.messages.acreate(
+ model="vertex_ai/claude-sonnet-4@20250514",
+ messages=[
+ {
+ "role": "user",
+ "content": "Search the web for information about AI"
+ }
+ ],
+ tools=[
+ {
+ "type": "tool_search_tool_bm25_20251119",
+ "name": "tool_search_tool_bm25"
+ },
+ {
+ "name": "search_web",
+ "description": "Search the web for information",
+ "input_schema": {
+ "type": "object",
+ "properties": {
+ "query": {
+ "type": "string",
+ "description": "The search query"
+ }
+ },
+ "required": ["query"]
+ },
+ "defer_loading": True
+ }
+ ],
+ max_tokens=1024,
+ extra_headers={"anthropic-beta": "tool-search-tool-2025-10-19"}
+)
+```
-1. **Keep frequently used tools non-deferred**: Your 3-5 most common tools should not have `defer_loading: true`
+#### Bedrock Messages Example
-2. **Use semantic descriptions**: Tool descriptions should use natural language that matches user queries
+```python showLineNumbers title="Bedrock Messages API (Invoke)"
+import litellm
-3. **Choose the right variant**:
- - Use **regex** for exact pattern matching (faster)
- - Use **BM25** for natural language semantic search
+response = await litellm.anthropic.messages.acreate(
+ model="bedrock/invoke/anthropic.claude-opus-4-20250514-v1:0",
+ messages=[
+ {
+ "role": "user",
+ "content": "What's the weather?"
+ }
+ ],
+ tools=[
+ {
+ "type": "tool_search_tool_regex_20251119",
+ "name": "tool_search_tool_regex"
+ },
+ {
+ "name": "get_weather",
+ "description": "Get weather information",
+ "input_schema": {
+ "type": "object",
+ "properties": {
+ "location": {"type": "string"}
+ },
+ "required": ["location"]
+ },
+ "defer_loading": True
+ }
+ ],
+ max_tokens=1024,
+ extra_headers={"anthropic-beta": "tool-search-tool-2025-10-19"}
+)
+```
-4. **Monitor usage**: Track `tool_search_requests` in the usage object to understand search patterns
+#### Streaming Support
-5. **Optimize tool catalog**: Remove unused tools and consolidate similar functionality
+```python showLineNumbers title="Messages API - Streaming"
+import litellm
+import json
-## When to Use Tool Search
+response = await litellm.anthropic.messages.acreate(
+ model="anthropic/claude-sonnet-4-20250514",
+ messages=[
+ {
+ "role": "user",
+ "content": "What's the weather in Tokyo?"
+ }
+ ],
+ tools=[
+ {
+ "type": "tool_search_tool_regex_20251119",
+ "name": "tool_search_tool_regex"
+ },
+ {
+ "name": "get_weather",
+ "description": "Get weather information",
+ "input_schema": {
+ "type": "object",
+ "properties": {
+ "location": {"type": "string"}
+ },
+ "required": ["location"]
+ },
+ "defer_loading": True
+ }
+ ],
+ max_tokens=1024,
+ stream=True,
+ extra_headers={"anthropic-beta": "advanced-tool-use-2025-11-20"}
+)
-**Good use cases:**
-- 10+ tools available in your system
-- Tool definitions consuming >10K tokens
-- Experiencing tool selection accuracy issues
-- Building systems with multiple tool categories
-- Tool library growing over time
+async for chunk in response:
+ if isinstance(chunk, bytes):
+ chunk_str = chunk.decode("utf-8")
+ for line in chunk_str.split("\n"):
+ if line.startswith("data: "):
+ try:
+ json_data = json.loads(line[6:])
+ print(json_data)
+ except json.JSONDecodeError:
+ pass
+```
-**When traditional tool calling is better:**
-- Less than 10 tools total
-- All tools are frequently used
-- Very small tool definitions (\<100 tokens total)
+### AI Gateway Usage
-## Limitations
+Configure the proxy to use Messages API endpoints.
-- Not compatible with tool use examples
-- Requires Claude Opus 4.5 or Sonnet 4.5
-- On Bedrock, only available via invoke API (not converse API)
-- On Bedrock, only supported for Claude Opus 4.5 (not Sonnet 4.5)
-- BM25 variant (`tool_search_tool_bm25_20251119`) is not supported on Bedrock
-- Maximum 10,000 tools in catalog
-- Returns 3-5 most relevant tools per search
+#### Proxy Configuration
-### Bedrock-Specific Notes
+```yaml showLineNumbers title="config.yaml"
+model_list:
+ - model_name: claude-sonnet-messages
+ litellm_params:
+ model: anthropic/claude-sonnet-4-20250514
+ api_key: os.environ/ANTHROPIC_API_KEY
+```
-When using Bedrock's Invoke API:
-- The regex variant (`tool_search_tool_regex_20251119`) is automatically normalized to `tool_search_tool_regex`
-- The BM25 variant (`tool_search_tool_bm25_20251119`) is automatically filtered out as it's not supported
-- Tool search is only available for Claude Opus 4.5 models
+#### Client Request
+
+```python showLineNumbers title="Client Request via Proxy (Messages API)"
+from anthropic import Anthropic
+
+client = Anthropic(
+ api_key="your-litellm-proxy-key",
+ base_url="http://0.0.0.0:4000"
+)
+
+response = client.messages.create(
+ model="claude-sonnet-messages",
+ max_tokens=1024,
+ messages=[
+ {
+ "role": "user",
+ "content": "What's the weather?"
+ }
+ ],
+ tools=[
+ {
+ "type": "tool_search_tool_regex_20251119",
+ "name": "tool_search_tool_regex"
+ },
+ {
+ "name": "get_weather",
+ "description": "Get weather information",
+ "input_schema": {
+ "type": "object",
+ "properties": {
+ "location": {"type": "string"}
+ },
+ "required": ["location"]
+ },
+ "defer_loading": True
+ }
+ ],
+ extra_headers={"anthropic-beta": "advanced-tool-use-2025-11-20"}
+)
+
+print(response)
+```
+
+---
## Additional Resources
- [Anthropic Tool Search Documentation](https://docs.anthropic.com/en/docs/build-with-claude/tool-use/tool-search)
- [LiteLLM Tool Calling Guide](https://docs.litellm.ai/docs/completion/function_call)
-
diff --git a/docs/my-website/docs/providers/azure_ai/azure_model_router.md b/docs/my-website/docs/providers/azure_ai/azure_model_router.md
index 5e14c7283f6..16bc1afb70e 100644
--- a/docs/my-website/docs/providers/azure_ai/azure_model_router.md
+++ b/docs/my-website/docs/providers/azure_ai/azure_model_router.md
@@ -5,19 +5,38 @@ Azure Model Router is a feature in Azure AI Foundry that automatically routes yo
## Key Features
- **Automatic Model Selection**: Azure Model Router dynamically selects the best model for your request
-- **Cost Tracking**: LiteLLM automatically tracks costs based on the actual model used (e.g., `gpt-4.1-nano`), not the router endpoint
+- **Cost Tracking**: LiteLLM automatically tracks costs based on the actual model used (e.g., `gpt-4.1-nano`), plus the Model Router infrastructure fee
- **Streaming Support**: Full support for streaming responses with accurate cost calculation
+- **Simple Configuration**: Easy to set up via UI or config file
+
+## Model Naming Pattern
+
+Use the pattern: `azure_ai/model_router/`
+
+**Components:**
+- `azure_ai` - The provider identifier
+- `model_router` - Indicates this is a Model Router deployment
+- `` - Your actual deployment name from Azure AI Foundry (e.g., `azure-model-router`)
+
+**Example:** `azure_ai/model_router/azure-model-router`
+
+**How it works:**
+- LiteLLM automatically strips the `model_router/` prefix when sending requests to Azure
+- Only your deployment name (e.g., `azure-model-router`) is sent to the Azure API
+- The full path is preserved in responses and logs for proper cost tracking
## LiteLLM Python SDK
### Basic Usage
+Use the pattern `azure_ai/model_router/` where `` is your Azure deployment name:
+
```python
import litellm
import os
response = litellm.completion(
- model="azure_ai/azure-model-router",
+ model="azure_ai/model_router/azure-model-router", # Use your deployment name
messages=[{"role": "user", "content": "Hello!"}],
api_base="https://your-endpoint.cognitiveservices.azure.com/openai/v1/",
api_key=os.getenv("AZURE_MODEL_ROUTER_API_KEY"),
@@ -26,6 +45,13 @@ response = litellm.completion(
print(response)
```
+**Pattern Explanation:**
+- `azure_ai` - The provider
+- `model_router` - Indicates this is a model router deployment
+- `azure-model-router` - Your actual deployment name from Azure AI Foundry
+
+LiteLLM will automatically strip the `model_router/` prefix when sending the request to Azure, so only `azure-model-router` is sent to the API.
+
### Streaming with Usage Tracking
```python
@@ -33,7 +59,7 @@ import litellm
import os
response = await litellm.acompletion(
- model="azure_ai/azure-model-router",
+ model="azure_ai/model_router/azure-model-router", # Use your deployment name
messages=[{"role": "user", "content": "hi"}],
api_base="https://your-endpoint.cognitiveservices.azure.com/openai/v1/",
api_key=os.getenv("AZURE_MODEL_ROUTER_API_KEY"),
@@ -51,13 +77,15 @@ async for chunk in response:
```yaml
model_list:
- - model_name: azure-model-router
+ - model_name: azure-model-router # Public name for your users
litellm_params:
- model: azure_ai/azure-model-router
+ model: azure_ai/model_router/azure-model-router # Use your deployment name
api_base: https://your-endpoint.cognitiveservices.azure.com/openai/v1/
api_key: os.environ/AZURE_MODEL_ROUTER_API_KEY
```
+**Note:** Replace `azure-model-router` in the model path with your actual deployment name from Azure AI Foundry.
+
### Start Proxy
```bash
@@ -80,49 +108,42 @@ curl -X POST http://localhost:4000/chat/completions \
This walkthrough shows how to add an Azure Model Router endpoint to LiteLLM using the Admin Dashboard.
-### Select Provider
+### Quick Start
+
+1. Navigate to the **Models** page in the LiteLLM UI
+2. Select **"Azure AI Foundry (Studio)"** as the provider
+3. Enter your deployment name (e.g., `azure-model-router`)
+4. LiteLLM will automatically format it as `azure_ai/model_router/azure-model-router`
+5. Add your API base URL and API key
+6. Test and save
+
+### Detailed Walkthrough
+
+#### Step 1: Select Provider
Navigate to the Models page and select "Azure AI Foundry (Studio)" as the provider.
-#### Navigate to Models Page
+##### Navigate to Models Page

-#### Click Provider Dropdown
+##### Click Provider Dropdown

-#### Choose Azure AI Foundry
+##### Choose Azure AI Foundry

-### Configure Model Name
+#### Step 2: Enter Deployment Name
-Set up the model name by entering `azure_ai/` followed by your model router deployment name from Azure.
+**New Simplified Method:** Just enter your deployment name directly in the text field. If your deployment name contains "model-router" or "model_router", LiteLLM will automatically format it as `azure_ai/model_router/`.
-#### Click Model Name Field
+**Example:**
+- Enter: `azure-model-router`
+- LiteLLM creates: `azure_ai/model_router/azure-model-router`
-
-
-#### Select Custom Model Name
-
-
-
-#### Enter LiteLLM Model Name
-
-
-
-#### Click Custom Model Name Field
-
-
-
-#### Type Model Prefix
-
-Type `azure_ai/` as the prefix.
-
-
-
-#### Copy Model Name from Azure Portal
+##### Copy Deployment Name from Azure Portal
Switch to Azure AI Foundry and copy your model router deployment name.
@@ -130,73 +151,79 @@ Switch to Azure AI Foundry and copy your model router deployment name.

-#### Paste Model Name
+##### Enter Deployment Name in LiteLLM
-Paste to get `azure_ai/azure-model-router`.
+Paste your deployment name (e.g., `azure-model-router`) directly into the text field.
-
+
-### Configure API Base and Key
+**What happens behind the scenes:**
+- You enter: `azure-model-router`
+- LiteLLM automatically detects this is a model router deployment
+- The full model path becomes: `azure_ai/model_router/azure-model-router`
+- When making API calls, only `azure-model-router` is sent to Azure
+
+#### Step 3: Configure API Base and Key
Copy the endpoint URL and API key from Azure portal.
-#### Copy API Base URL from Azure
+##### Copy API Base URL from Azure

-#### Enter API Base in LiteLLM
+##### Enter API Base in LiteLLM


-#### Copy API Key from Azure
+##### Copy API Key from Azure

-#### Enter API Key in LiteLLM
+##### Enter API Key in LiteLLM

-### Test and Add Model
+#### Step 4: Test and Add Model
Verify your configuration works and save the model.
-#### Test Connection
+##### Test Connection

-#### Close Test Dialog
+##### Close Test Dialog

-#### Add Model
+##### Add Model

-### Verify in Playground
+#### Step 5: Verify in Playground
Test your model and verify cost tracking is working.
-#### Open Playground
+##### Open Playground

-#### Select Model
+##### Select Model

-#### Send Test Message
+##### Send Test Message

-#### View Logs
+##### View Logs

-#### Verify Cost Tracking
+##### Verify Cost Tracking
-Cost is tracked based on the actual model used (e.g., `gpt-4.1-nano`).
+Cost is tracked based on the actual model used (e.g., `gpt-4.1-nano`), plus a flat infrastructure cost of $0.14 per million input tokens for using the Model Router.

@@ -205,28 +232,50 @@ Cost is tracked based on the actual model used (e.g., `gpt-4.1-nano`).
LiteLLM automatically handles cost tracking for Azure Model Router by:
1. **Detecting the actual model**: When Azure Model Router routes your request to a specific model (e.g., `gpt-4.1-nano-2025-04-14`), LiteLLM extracts this from the response
-2. **Calculating accurate costs**: Costs are calculated based on the actual model used, not the router endpoint name
+2. **Calculating accurate costs**: Costs are calculated based on:
+ - The actual model used (e.g., `gpt-4.1-nano` token costs)
+ - Plus a flat infrastructure cost of **$0.14 per million input tokens** for using the Model Router
3. **Streaming support**: Cost tracking works correctly for both streaming and non-streaming requests
+### Cost Breakdown
+
+When you use Azure Model Router, the total cost includes:
+
+- **Model Cost**: Based on the actual model that handled your request (e.g., `gpt-4.1-nano`)
+- **Router Flat Cost**: $0.14 per million input tokens (Azure AI Foundry infrastructure fee)
+
### Example Response with Cost
```python
import litellm
response = litellm.completion(
- model="azure_ai/azure-model-router",
+ model="azure_ai/model_router/azure-model-router",
messages=[{"role": "user", "content": "Hello!"}],
api_base="https://your-endpoint.cognitiveservices.azure.com/openai/v1/",
api_key="your-api-key",
)
# The response will show the actual model used
-print(f"Model used: {response.model}") # e.g., "gpt-4.1-nano-2025-04-14"
+print(f"Model used: {response.model}") # e.g., "azure_ai/gpt-4.1-nano-2025-04-14"
-# Get cost
+# Get cost (includes both model cost and router flat cost)
from litellm import completion_cost
cost = completion_cost(completion_response=response)
-print(f"Cost: ${cost}")
+print(f"Total cost: ${cost}")
+
+# Access detailed cost breakdown
+if hasattr(response, '_hidden_params') and 'response_cost' in response._hidden_params:
+ print(f"Response cost: ${response._hidden_params['response_cost']}")
```
+### Viewing Cost Breakdown in UI
+
+When viewing logs in the LiteLLM UI, you'll see:
+- **Model Cost**: The cost for the actual model used
+- **Azure Model Router Flat Cost**: The $0.14/M input tokens infrastructure fee
+- **Total Cost**: Sum of both costs
+
+This breakdown helps you understand exactly what you're paying for when using the Model Router.
+
diff --git a/docs/my-website/docs/providers/bedrock.md b/docs/my-website/docs/providers/bedrock.md
index 487212ad655..e546ed97656 100644
--- a/docs/my-website/docs/providers/bedrock.md
+++ b/docs/my-website/docs/providers/bedrock.md
@@ -9,7 +9,7 @@ ALL Bedrock models (Anthropic, Meta, Deepseek, Mistral, Amazon, etc.) are Suppor
| Description | Amazon Bedrock is a fully managed service that offers a choice of high-performing foundation models (FMs). |
| Provider Route on LiteLLM | `bedrock/`, [`bedrock/converse/`](#set-converse--invoke-route), [`bedrock/invoke/`](#set-invoke-route), [`bedrock/converse_like/`](#calling-via-internal-proxy), [`bedrock/llama/`](#deepseek-not-r1), [`bedrock/deepseek_r1/`](#deepseek-r1), [`bedrock/qwen3/`](#qwen3-imported-models), [`bedrock/qwen2/`](./bedrock_imported.md#qwen2-imported-models), [`bedrock/openai/`](./bedrock_imported.md#openai-compatible-imported-models-qwen-25-vl-etc), [`bedrock/moonshot`](./bedrock_imported.md#moonshot-kimi-k2-thinking) |
| Provider Doc | [Amazon Bedrock ↗](https://docs.aws.amazon.com/bedrock/latest/userguide/what-is-bedrock.html) |
-| Supported OpenAI Endpoints | `/chat/completions`, `/completions`, `/embeddings`, `/images/generations` |
+| Supported OpenAI Endpoints | `/chat/completions`, `/completions`, `/embeddings`, `/images/generations`, `/v1/realtime`|
| Rerank Endpoint | `/rerank` |
| Pass-through Endpoint | [Supported](../pass_through/bedrock.md) |
diff --git a/docs/my-website/docs/providers/bedrock_realtime_with_audio.md b/docs/my-website/docs/providers/bedrock_realtime_with_audio.md
new file mode 100644
index 00000000000..a2d9813ffd9
--- /dev/null
+++ b/docs/my-website/docs/providers/bedrock_realtime_with_audio.md
@@ -0,0 +1,362 @@
+# Bedrock Realtime API
+
+## Overview
+
+Amazon Bedrock's Nova Sonic model supports real-time bidirectional audio streaming for voice conversations. This tutorial shows how to use it through LiteLLM Proxy.
+
+## Setup
+
+### 1. Configure LiteLLM Proxy
+
+Create a `config.yaml` file:
+
+```yaml
+model_list:
+ - model_name: "bedrock-sonic"
+ litellm_params:
+ model: bedrock/amazon.nova-sonic-v1:0
+ aws_region_name: us-east-1 # or your preferred region
+ model_info:
+ mode: realtime
+```
+
+### 2. Start LiteLLM Proxy
+
+```bash
+litellm --config config.yaml
+```
+
+## Basic Text Interaction
+
+```python
+import asyncio
+import websockets
+import json
+
+LITELLM_API_KEY = "sk-1234" # Your LiteLLM API key
+LITELLM_URL = 'ws://localhost:4000/v1/realtime?model=bedrock-sonic'
+
+async def test_text_conversation():
+ async with websockets.connect(
+ LITELLM_URL,
+ additional_headers={
+ "Authorization": f"Bearer {LITELLM_API_KEY}"
+ }
+ ) as ws:
+ # Wait for session.created
+ response = await ws.recv()
+ print(f"Connected: {json.loads(response)['type']}")
+
+ # Configure session
+ session_update = {
+ "type": "session.update",
+ "session": {
+ "instructions": "You are a helpful assistant.",
+ "modalities": ["text"],
+ "temperature": 0.8
+ }
+ }
+ await ws.send(json.dumps(session_update))
+
+ # Send a message
+ message = {
+ "type": "conversation.item.create",
+ "item": {
+ "type": "message",
+ "role": "user",
+ "content": [{"type": "input_text", "text": "Hello!"}]
+ }
+ }
+ await ws.send(json.dumps(message))
+
+ # Trigger response
+ await ws.send(json.dumps({"type": "response.create"}))
+
+ # Listen for response
+ while True:
+ response = await ws.recv()
+ event = json.loads(response)
+
+ if event['type'] == 'response.text.delta':
+ print(event['delta'], end='', flush=True)
+ elif event['type'] == 'response.done':
+ print("\n✓ Complete")
+ break
+
+if __name__ == "__main__":
+ asyncio.run(test_text_conversation())
+```
+
+## Audio Streaming with Voice Conversation
+
+```python
+import asyncio
+import websockets
+import json
+import base64
+import pyaudio
+
+LITELLM_API_KEY = "sk-1234"
+LITELLM_URL = 'ws://localhost:4000/v1/realtime?model=bedrock-sonic'
+
+# Audio configuration
+INPUT_RATE = 16000 # Nova Sonic expects 16kHz input
+OUTPUT_RATE = 24000 # Nova Sonic outputs 24kHz
+CHUNK = 1024
+
+async def audio_conversation():
+ # Initialize PyAudio
+ p = pyaudio.PyAudio()
+
+ # Input stream (microphone)
+ input_stream = p.open(
+ format=pyaudio.paInt16,
+ channels=1,
+ rate=INPUT_RATE,
+ input=True,
+ frames_per_buffer=CHUNK
+ )
+
+ # Output stream (speakers)
+ output_stream = p.open(
+ format=pyaudio.paInt16,
+ channels=1,
+ rate=OUTPUT_RATE,
+ output=True,
+ frames_per_buffer=CHUNK
+ )
+
+ async with websockets.connect(
+ LITELLM_URL,
+ additional_headers={"Authorization": f"Bearer {LITELLM_API_KEY}"}
+ ) as ws:
+ # Wait for session.created
+ await ws.recv()
+ print("✓ Connected")
+
+ # Configure session with audio
+ session_update = {
+ "type": "session.update",
+ "session": {
+ "instructions": "You are a friendly voice assistant.",
+ "modalities": ["text", "audio"],
+ "voice": "matthew",
+ "input_audio_format": "pcm16",
+ "output_audio_format": "pcm16"
+ }
+ }
+ await ws.send(json.dumps(session_update))
+ print("🎤 Speak into your microphone...")
+
+ async def send_audio():
+ """Capture and send audio from microphone"""
+ while True:
+ audio_data = input_stream.read(CHUNK, exception_on_overflow=False)
+ audio_b64 = base64.b64encode(audio_data).decode('utf-8')
+ await ws.send(json.dumps({
+ "type": "input_audio_buffer.append",
+ "audio": audio_b64
+ }))
+ await asyncio.sleep(0.01)
+
+ async def receive_audio():
+ """Receive and play audio responses"""
+ while True:
+ response = await ws.recv()
+ event = json.loads(response)
+
+ if event['type'] == 'response.audio.delta':
+ audio_b64 = event.get('delta', '')
+ if audio_b64:
+ audio_bytes = base64.b64decode(audio_b64)
+ output_stream.write(audio_bytes)
+
+ elif event['type'] == 'response.text.delta':
+ print(event['delta'], end='', flush=True)
+
+ elif event['type'] == 'response.done':
+ print("\n✓ Response complete")
+
+ # Run both tasks concurrently
+ await asyncio.gather(send_audio(), receive_audio())
+
+if __name__ == "__main__":
+ try:
+ asyncio.run(audio_conversation())
+ except KeyboardInterrupt:
+ print("\n\nGoodbye!")
+```
+
+## Using Tools/Function Calling
+
+```python
+import asyncio
+import websockets
+import json
+from datetime import datetime
+
+LITELLM_API_KEY = "sk-1234"
+LITELLM_URL = 'ws://localhost:4000/v1/realtime?model=bedrock-sonic'
+
+# Define tools
+TOOLS = [
+ {
+ "type": "function",
+ "function": {
+ "name": "get_weather",
+ "description": "Get current weather for a location",
+ "parameters": {
+ "type": "object",
+ "properties": {
+ "location": {
+ "type": "string",
+ "description": "City name"
+ }
+ },
+ "required": ["location"]
+ }
+ }
+ }
+]
+
+def get_weather(location: str) -> dict:
+ """Simulated weather function"""
+ return {
+ "location": location,
+ "temperature": 72,
+ "conditions": "sunny"
+ }
+
+async def conversation_with_tools():
+ async with websockets.connect(
+ LITELLM_URL,
+ additional_headers={"Authorization": f"Bearer {LITELLM_API_KEY}"}
+ ) as ws:
+ # Wait for session.created
+ await ws.recv()
+
+ # Configure session with tools
+ session_update = {
+ "type": "session.update",
+ "session": {
+ "instructions": "You are a helpful assistant with access to tools.",
+ "modalities": ["text"],
+ "tools": TOOLS
+ }
+ }
+ await ws.send(json.dumps(session_update))
+
+ # Send a message that requires a tool
+ message = {
+ "type": "conversation.item.create",
+ "item": {
+ "type": "message",
+ "role": "user",
+ "content": [{"type": "input_text", "text": "What's the weather in San Francisco?"}]
+ }
+ }
+ await ws.send(json.dumps(message))
+ await ws.send(json.dumps({"type": "response.create"}))
+
+ # Handle responses and tool calls
+ while True:
+ response = await ws.recv()
+ event = json.loads(response)
+
+ if event['type'] == 'response.text.delta':
+ print(event['delta'], end='', flush=True)
+
+ elif event['type'] == 'response.function_call_arguments.done':
+ # Execute the tool
+ function_name = event['name']
+ arguments = json.loads(event['arguments'])
+
+ print(f"\n🔧 Calling {function_name}({arguments})")
+ result = get_weather(**arguments)
+
+ # Send tool result back
+ tool_result = {
+ "type": "conversation.item.create",
+ "item": {
+ "type": "function_call_output",
+ "call_id": event['call_id'],
+ "output": json.dumps(result)
+ }
+ }
+ await ws.send(json.dumps(tool_result))
+ await ws.send(json.dumps({"type": "response.create"}))
+
+ elif event['type'] == 'response.done':
+ print("\n✓ Complete")
+ break
+
+if __name__ == "__main__":
+ asyncio.run(conversation_with_tools())
+```
+
+## Configuration Options
+
+### Voice Options
+Available voices: `matthew`, `joanna`, `ruth`, `stephen`, `gregory`, `amy`
+
+### Audio Formats
+- **Input**: 16kHz PCM16 (mono)
+- **Output**: 24kHz PCM16 (mono)
+
+### Modalities
+- `["text"]` - Text only
+- `["audio"]` - Audio only
+- `["text", "audio"]` - Both text and audio
+
+## Example Test Scripts
+
+Complete working examples are available in the LiteLLM repository:
+
+- **Basic audio streaming**: `test_bedrock_realtime_client.py`
+- **Simple text test**: `test_bedrock_realtime_simple.py`
+- **Tool calling**: `test_bedrock_realtime_tools.py`
+
+## Requirements
+
+```bash
+pip install litellm websockets pyaudio
+```
+
+## AWS Configuration
+
+Ensure your AWS credentials are configured:
+
+```bash
+export AWS_ACCESS_KEY_ID=your_access_key
+export AWS_SECRET_ACCESS_KEY=your_secret_key
+export AWS_REGION_NAME=us-east-1
+```
+
+Or use AWS CLI configuration:
+
+```bash
+aws configure
+```
+
+## Troubleshooting
+
+### Connection Issues
+- Ensure LiteLLM proxy is running on the correct port
+- Verify AWS credentials are properly configured
+- Check that the Bedrock model is available in your region
+
+### Audio Issues
+- Verify PyAudio is properly installed
+- Check microphone/speaker permissions
+- Ensure correct sample rates (16kHz input, 24kHz output)
+
+### Tool Calling Issues
+- Ensure tools are properly defined in session.update
+- Verify tool results are sent back with correct call_id
+- Check that response.create is sent after tool result
+
+## Related Resources
+
+- [OpenAI Realtime API Documentation](https://platform.openai.com/docs/guides/realtime)
+- [Amazon Bedrock Nova Sonic Documentation](https://docs.aws.amazon.com/bedrock/latest/userguide/nova-sonic.html)
+- [LiteLLM Realtime API Documentation](/docs/realtime)
diff --git a/docs/my-website/docs/providers/elevenlabs.md b/docs/my-website/docs/providers/elevenlabs.md
index 5cf62f51203..b4ed3d3346b 100644
--- a/docs/my-website/docs/providers/elevenlabs.md
+++ b/docs/my-website/docs/providers/elevenlabs.md
@@ -243,6 +243,13 @@ ElevenLabs provides high-quality text-to-speech capabilities through their TTS A
| Supported Operations | `/audio/speech` |
| Link to Provider Doc | [ElevenLabs TTS API ↗](https://elevenlabs.io/docs/api-reference/text-to-speech) |
+### Supported Models
+
+| Model | Route | Description |
+|-------|-------|-------------|
+| Eleven v3 | `elevenlabs/eleven_v3` | Most expressive model. 70+ languages, audio tags support for sound effects and pauses. |
+| Eleven Multilingual v2 | `elevenlabs/eleven_multilingual_v2` | Default TTS model. 29 languages, stable and production-ready. |
+
### Quick Start
#### LiteLLM Python SDK
@@ -265,6 +272,26 @@ with open("test_output.mp3", "wb") as f:
f.write(audio.read())
```
+#### Using Eleven v3 with Audio Tags
+
+Eleven v3 supports [audio tags](https://elevenlabs.io/docs/overview/capabilities/text-to-speech#audio-tags) for adding sound effects and pauses directly in the text:
+
+```python showLineNumbers title="Eleven v3 with audio tags"
+import litellm
+import os
+
+os.environ["ELEVENLABS_API_KEY"] = "your-elevenlabs-api-key"
+
+audio = litellm.speech(
+ model="elevenlabs/eleven_v3",
+ input='Welcome back. applause Today we have a special guest. Let me introduce them.',
+ voice="alloy",
+)
+
+with open("eleven_v3_output.mp3", "wb") as f:
+ f.write(audio.read())
+```
+
#### Advanced Usage: Overriding Parameters and ElevenLabs-Specific Features
```python showLineNumbers title="Advanced TTS with custom parameters"
diff --git a/docs/my-website/docs/providers/gemini.md b/docs/my-website/docs/providers/gemini.md
index 23a02f7365c..b9ad7820dd4 100644
--- a/docs/my-website/docs/providers/gemini.md
+++ b/docs/my-website/docs/providers/gemini.md
@@ -1840,6 +1840,57 @@ content = response.get('choices', [{}])[0].get('message', {}).get('content')
print(content)
```
+## gemini-robotics-er-1.5-preview Usage
+
+```python
+from litellm import api_base
+from openai import OpenAI
+import os
+import base64
+
+client = OpenAI(base_url="http://0.0.0.0:4000", api_key="sk-12345")
+base64_image = base64.b64encode(open("closeup-object-on-table-many-260nw-1216144471.webp", "rb").read()).decode()
+
+import json
+import re
+tools = [{"codeExecution": {}}]
+response = client.chat.completions.create(
+ model="gemini/gemini-robotics-er-1.5-preview",
+ messages=[
+ {
+ "role": "user",
+ "content": [
+ {
+ "type": "text",
+ "text": "Point to no more than 10 items in the image. The label returned should be an identifying name for the object detected. The answer should follow the json format: [{\"point\": [y, x], \"label\": }, ...]. The points are in [y, x] format normalized to 0-1000."
+ },
+ {
+ "type": "image_url",
+ "image_url": {"url": f"data:image/jpeg;base64,{base64_image}"}
+ }
+ ]
+ }
+ ],
+ tools=tools
+)
+
+# Extract JSON from markdown code block if present
+content = response.choices[0].message.content
+# Look for triple-backtick JSON block
+match = re.search(r'```json\s*(.*?)\s*```', content, re.DOTALL)
+if match:
+ json_str = match.group(1)
+else:
+ json_str = content
+
+try:
+ data = json.loads(json_str)
+ print(json.dumps(data, indent=2))
+except Exception as e:
+ print("Error parsing response as JSON:", e)
+ print("Response content:", content)
+```
+
## Usage - PDF / Videos / etc. Files
### Inline Data (e.g. audio stream)
diff --git a/docs/my-website/docs/providers/github_copilot.md b/docs/my-website/docs/providers/github_copilot.md
index 306c9f949ec..e9fd3444f5f 100644
--- a/docs/my-website/docs/providers/github_copilot.md
+++ b/docs/my-website/docs/providers/github_copilot.md
@@ -35,11 +35,10 @@ from litellm import completion
response = completion(
model="github_copilot/gpt-4",
- messages=[{"role": "user", "content": "Write a Python function to calculate fibonacci numbers"}],
- extra_headers={
- "editor-version": "vscode/1.85.1",
- "Copilot-Integration-Id": "vscode-chat"
- }
+ messages=[
+ {"role": "system", "content": "You are a helpful coding assistant"},
+ {"role": "user", "content": "Write a Python function to calculate fibonacci numbers"}
+ ]
)
print(response)
```
@@ -50,11 +49,7 @@ from litellm import completion
stream = completion(
model="github_copilot/gpt-4",
messages=[{"role": "user", "content": "Explain async/await in Python"}],
- stream=True,
- extra_headers={
- "editor-version": "vscode/1.85.1",
- "Copilot-Integration-Id": "vscode-chat"
- }
+ stream=True
)
for chunk in stream:
@@ -134,11 +129,7 @@ client = OpenAI(
# Non-streaming response
response = client.chat.completions.create(
model="github_copilot/gpt-4",
- messages=[{"role": "user", "content": "How do I optimize this SQL query?"}],
- extra_headers={
- "editor-version": "vscode/1.85.1",
- "Copilot-Integration-Id": "vscode-chat"
- }
+ messages=[{"role": "user", "content": "How do I optimize this SQL query?"}]
)
print(response.choices[0].message.content)
@@ -156,11 +147,7 @@ response = litellm.completion(
model="litellm_proxy/github_copilot/gpt-4",
messages=[{"role": "user", "content": "Review this code for bugs"}],
api_base="http://localhost:4000",
- api_key="your-proxy-api-key",
- extra_headers={
- "editor-version": "vscode/1.85.1",
- "Copilot-Integration-Id": "vscode-chat"
- }
+ api_key="your-proxy-api-key"
)
print(response.choices[0].message.content)
@@ -174,8 +161,6 @@ print(response.choices[0].message.content)
curl http://localhost:4000/v1/chat/completions \
-H "Content-Type: application/json" \
-H "Authorization: Bearer your-proxy-api-key" \
- -H "editor-version: vscode/1.85.1" \
- -H "Copilot-Integration-Id: vscode-chat" \
-d '{
"model": "github_copilot/gpt-4",
"messages": [{"role": "user", "content": "Explain this error message"}]
@@ -211,9 +196,11 @@ export GITHUB_COPILOT_API_KEY_FILE="api-key.json"
### Headers
-GitHub Copilot supports various editor-specific headers:
+LiteLLM automatically injects the required GitHub Copilot headers (simulating VSCode). You don't need to specify them manually.
-```python showLineNumbers title="Common Headers"
+If you want to override the defaults (e.g., to simulate a different editor), you can use `extra_headers`:
+
+```python showLineNumbers title="Custom Headers (Optional)"
extra_headers = {
"editor-version": "vscode/1.85.1", # Editor version
"editor-plugin-version": "copilot/1.155.0", # Plugin version
diff --git a/docs/my-website/docs/providers/sarvam.md b/docs/my-website/docs/providers/sarvam.md
new file mode 100644
index 00000000000..6a292456781
--- /dev/null
+++ b/docs/my-website/docs/providers/sarvam.md
@@ -0,0 +1,92 @@
+# Sarvam.ai
+
+import Tabs from '@theme/Tabs';
+import TabItem from '@theme/TabItem';
+
+LiteLLM supports all the text models from [Sarvam ai](https://docs.sarvam.ai/api-reference-docs/chat/chat-completions)
+
+## Usage
+
+```python
+import os
+from litellm import completion
+
+# Set your Sarvam API key
+os.environ["SARVAM_API_KEY"] = ""
+
+messages = [{"role": "user", "content": "Hello"}]
+
+response = completion(
+ model="sarvam/sarvam-m",
+ messages=messages,
+)
+print(response)
+```
+
+## Usage with LiteLLM Proxy Server
+
+Here's how to call a Sarvam.ai model with the LiteLLM Proxy Server
+
+1. **Modify the `config.yaml`:**
+
+ ```yaml
+ model_list:
+ - model_name: my-model
+ litellm_params:
+ model: sarvam/ # add sarvam/ prefix to route as Sarvam provider
+ api_key: api-key # api key to send your model
+ ```
+
+2. **Start the proxy:**
+
+ ```bash
+ $ litellm --config /path/to/config.yaml
+ ```
+
+3. **Send a request to LiteLLM Proxy Server:**
+
+
+
+
+
+ ```python
+ import openai
+
+ client = openai.OpenAI(
+ api_key="sk-1234", # pass litellm proxy key, if you're using virtual keys
+ base_url="http://0.0.0.0:4000" # litellm-proxy-base url
+ )
+
+ response = client.chat.completions.create(
+ model="my-model",
+ messages=[
+ {
+ "role": "user",
+ "content": "what llm are you"
+ }
+ ],
+ )
+
+ print(response)
+ ```
+
+
+
+
+ ```shell
+ curl --location 'http://0.0.0.0:4000/chat/completions' \
+ --header 'Authorization: Bearer sk-1234' \
+ --header 'Content-Type: application/json' \
+ --data '{
+ "model": "my-model",
+ "messages": [
+ {
+ "role": "user",
+ "content": "what llm are you"
+ }
+ ]
+ }'
+ ```
+
+
+
diff --git a/docs/my-website/docs/providers/vercel_ai_gateway.md b/docs/my-website/docs/providers/vercel_ai_gateway.md
index 91f0a18ea1c..3ff007171ed 100644
--- a/docs/my-website/docs/providers/vercel_ai_gateway.md
+++ b/docs/my-website/docs/providers/vercel_ai_gateway.md
@@ -11,7 +11,7 @@ import TabItem from '@theme/TabItem';
| Provider Route on LiteLLM | `vercel_ai_gateway/` |
| Link to Provider Doc | [Vercel AI Gateway Documentation ↗](https://vercel.com/docs/ai-gateway) |
| Base URL | `https://ai-gateway.vercel.sh/v1` |
-| Supported Operations | `/chat/completions`, `/models` |
+| Supported Operations | `/chat/completions`, `/embeddings`, `/models` |
@@ -73,7 +73,7 @@ messages = [{"content": "Hello, how are you?", "role": "user"}]
# Vercel AI Gateway call with streaming
response = completion(
- model="vercel_ai_gateway/openai/gpt-4o",
+ model="vercel_ai_gateway/openai/gpt-4o",
messages=messages,
stream=True
)
@@ -82,6 +82,33 @@ for chunk in response:
print(chunk)
```
+### Embeddings
+
+```python showLineNumbers title="Vercel AI Gateway Embeddings"
+import os
+from litellm import embedding
+
+os.environ["VERCEL_AI_GATEWAY_API_KEY"] = "your-api-key"
+
+# Vercel AI Gateway embedding call
+response = embedding(
+ model="vercel_ai_gateway/openai/text-embedding-3-small",
+ input="Hello world"
+)
+
+print(response.data[0]["embedding"][:5]) # Print first 5 dimensions
+```
+
+You can also specify the `dimensions` parameter:
+
+```python showLineNumbers title="Vercel AI Gateway Embeddings with Dimensions"
+response = embedding(
+ model="vercel_ai_gateway/openai/text-embedding-3-small",
+ input=["Hello world", "Goodbye world"],
+ dimensions=768
+)
+```
+
## Usage - LiteLLM Proxy
Add the following to your LiteLLM Proxy configuration file:
@@ -97,6 +124,11 @@ model_list:
litellm_params:
model: vercel_ai_gateway/anthropic/claude-4-sonnet
api_key: os.environ/VERCEL_AI_GATEWAY_API_KEY
+
+ - model_name: text-embedding-3-small-gateway
+ litellm_params:
+ model: vercel_ai_gateway/openai/text-embedding-3-small
+ api_key: os.environ/VERCEL_AI_GATEWAY_API_KEY
```
Start your LiteLLM Proxy server:
diff --git a/docs/my-website/docs/providers/vertex_speech.md b/docs/my-website/docs/providers/vertex_speech.md
index d0acacb5aec..751782a323c 100644
--- a/docs/my-website/docs/providers/vertex_speech.md
+++ b/docs/my-website/docs/providers/vertex_speech.md
@@ -312,6 +312,7 @@ Gemini models with audio output capabilities using the chat completions API.
- Only supports `pcm16` audio format
- Streaming not yet supported
- Must set `modalities: ["audio"]`
+- When using via LiteLLM Proxy, must include `"allowed_openai_params": ["audio", "modalities"]` in the request body to enable audio parameters
:::
### Quick Start
@@ -372,7 +373,8 @@ curl http://0.0.0.0:4000/v1/chat/completions \
"model": "gemini-tts",
"messages": [{"role": "user", "content": "Say hello in a friendly voice"}],
"modalities": ["audio"],
- "audio": {"voice": "Kore", "format": "pcm16"}
+ "audio": {"voice": "Kore", "format": "pcm16"},
+ "allowed_openai_params": ["audio", "modalities"]
}'
```
@@ -389,6 +391,7 @@ response = client.chat.completions.create(
messages=[{"role": "user", "content": "Say hello in a friendly voice"}],
modalities=["audio"],
audio={"voice": "Kore", "format": "pcm16"},
+ extra_body={"allowed_openai_params": ["audio", "modalities"]}
)
print(response)
```
diff --git a/docs/my-website/docs/providers/xai_realtime.md b/docs/my-website/docs/providers/xai_realtime.md
new file mode 100644
index 00000000000..b36908c4686
--- /dev/null
+++ b/docs/my-website/docs/providers/xai_realtime.md
@@ -0,0 +1,308 @@
+import Tabs from '@theme/Tabs';
+import TabItem from '@theme/TabItem';
+
+# xAI Voice Agent (Realtime API)
+
+xAI's Grok Voice Agent provides real-time voice conversation capabilities through WebSocket connections, enabling natural bidirectional audio interactions.
+
+| Feature | Description | Comments |
+| --- | --- | --- |
+| LiteLLM AI Gateway | ✅ | |
+| LiteLLM Python SDK | ✅ | Full support via `litellm.realtime()` |
+
+## Quick Start
+
+### Supported Model
+
+| Model | Context | Features |
+|-------|---------|----------|
+| `xai/grok-4-1-fast-non-reasoning` | 2M tokens | Voice conversation, Function calling, Vision, Audio, Web search, Caching |
+
+**Note:** xAI Realtime API uses the non-reasoning variant for optimal real-time performance.
+
+## Python SDK Usage
+
+### Basic Realtime Connection
+
+```python
+import asyncio
+from litellm import realtime
+
+async def test_xai_realtime():
+ """
+ Test xAI Grok Voice Agent via LiteLLM SDK
+ """
+ # Initialize realtime connection
+ ws = await realtime(
+ model="xai/grok-4-1-fast-non-reasoning",
+ api_key="your-xai-api-key", # or set XAI_API_KEY env var
+ )
+
+ # Connection established, xAI sends "conversation.created" event
+ print("Connected to xAI Grok Voice Agent")
+
+ # Send a message
+ await ws.send_text(json.dumps({
+ "type": "conversation.item.create",
+ "item": {
+ "type": "message",
+ "role": "user",
+ "content": [{
+ "type": "input_text",
+ "text": "Hello! How are you?"
+ }]
+ }
+ }))
+
+ # Request a response
+ await ws.send_text(json.dumps({
+ "type": "response.create"
+ }))
+
+ # Listen for responses
+ async for message in ws:
+ data = json.loads(message)
+ print(f"Received: {data['type']}")
+
+ if data['type'] == 'response.done':
+ break
+
+ await ws.close()
+
+# Run the async function
+asyncio.run(test_xai_realtime())
+```
+
+### With Audio Input/Output
+
+```python
+import asyncio
+import json
+from litellm import realtime
+
+async def xai_voice_conversation():
+ """
+ Voice conversation with xAI Grok Voice Agent
+ """
+ ws = await realtime(
+ model="xai/grok-4-1-fast-non-reasoning",
+ api_key="your-xai-api-key",
+ )
+
+ # Send audio data (base64 encoded PCM16 24kHz)
+ await ws.send_text(json.dumps({
+ "type": "conversation.item.create",
+ "item": {
+ "type": "message",
+ "role": "user",
+ "content": [{
+ "type": "input_audio",
+ "audio": "base64_encoded_audio_data_here"
+ }]
+ }
+ }))
+
+ # Request response with audio
+ await ws.send_text(json.dumps({
+ "type": "response.create",
+ "response": {
+ "modalities": ["text", "audio"],
+ "instructions": "Please respond in a friendly tone."
+ }
+ }))
+
+ # Process streaming audio response
+ async for message in ws:
+ data = json.loads(message)
+
+ if data['type'] == 'response.audio.delta':
+ # Handle audio chunks
+ audio_chunk = data['delta']
+ # Process audio_chunk (play it, save it, etc.)
+
+ elif data['type'] == 'response.done':
+ break
+
+ await ws.close()
+
+asyncio.run(xai_voice_conversation())
+```
+
+## LiteLLM Proxy (AI Gateway) Usage
+
+Load balance across multiple xAI deployments or combine with other providers.
+
+### 1. Add Model to Config
+
+```yaml
+model_list:
+ - model_name: grok-voice-agent
+ litellm_params:
+ model: xai/grok-4-1-fast-non-reasoning
+ api_key: os.environ/XAI_API_KEY
+ model_info:
+ mode: realtime
+
+ # Optional: Add fallback to OpenAI
+ - model_name: grok-voice-agent
+ litellm_params:
+ model: openai/gpt-4o-realtime-preview-2024-10-01
+ api_key: os.environ/OPENAI_API_KEY
+ model_info:
+ mode: realtime
+```
+
+### 2. Start Proxy
+
+```bash
+litellm --config /path/to/config.yaml
+
+# RUNNING on http://0.0.0.0:4000
+```
+
+### 3. Test Connection
+
+#### Python Client
+
+```python
+import asyncio
+import websockets
+import json
+
+async def test_proxy():
+ url = "ws://0.0.0.0:4000/v1/realtime?model=grok-voice-agent"
+
+ async with websockets.connect(
+ url,
+ extra_headers={
+ "Authorization": "Bearer sk-1234", # Your LiteLLM proxy key
+ "OpenAI-Beta": "realtime=v1"
+ }
+ ) as ws:
+ # Wait for conversation.created event from xAI
+ message = await ws.recv()
+ print(f"Connected: {message}")
+
+ # Send a message
+ await ws.send(json.dumps({
+ "type": "conversation.item.create",
+ "item": {
+ "type": "message",
+ "role": "user",
+ "content": [{
+ "type": "input_text",
+ "text": "Hello from LiteLLM proxy!"
+ }]
+ }
+ }))
+
+ # Request response
+ await ws.send(json.dumps({
+ "type": "response.create"
+ }))
+
+ # Listen for response
+ async for message in ws:
+ data = json.loads(message)
+ print(f"Event: {data['type']}")
+
+ if data['type'] == 'response.done':
+ break
+
+asyncio.run(test_proxy())
+```
+
+#### Node.js Client
+
+```javascript
+// test.js - Run with: node test.js
+const WebSocket = require("ws");
+
+const url = "ws://0.0.0.0:4000/v1/realtime?model=grok-voice-agent";
+
+const ws = new WebSocket(url, {
+ headers: {
+ "Authorization": "Bearer sk-1234",
+ "OpenAI-Beta": "realtime=v1",
+ },
+});
+
+ws.on("open", function open() {
+ console.log("Connected to xAI via LiteLLM proxy");
+
+ // Send a message
+ ws.send(JSON.stringify({
+ type: "conversation.item.create",
+ item: {
+ type: "message",
+ role: "user",
+ content: [{
+ type: "input_text",
+ text: "What's the weather like?"
+ }]
+ }
+ }));
+
+ // Request response
+ ws.send(JSON.stringify({
+ type: "response.create",
+ response: {
+ modalities: ["text"],
+ instructions: "Please assist the user."
+ }
+ }));
+});
+
+ws.on("message", function incoming(message) {
+ const data = JSON.parse(message.toString());
+ console.log(`Event: ${data.type}`);
+
+ if (data.type === 'response.done') {
+ ws.close();
+ }
+});
+
+ws.on("error", function handleError(error) {
+ console.error("Error: ", error);
+});
+```
+
+## Key Differences from OpenAI
+
+xAI's Grok Voice Agent has some differences from OpenAI's Realtime API:
+
+| Feature | xAI | OpenAI | LiteLLM Handling |
+|---------|-----|--------|------------------|
+| Initial Event | `conversation.created` | `session.created` | ⚠️ Passed through as-is |
+| WebSocket URL | `wss://api.x.ai/v1/realtime` | `wss://api.openai.com/v1/realtime` | ✅ Auto-configured |
+| Model | `grok-4-1-fast-non-reasoning` | `gpt-4o-realtime-preview` | ✅ Via model prefix |
+| Audio Format | PCM16 24kHz mono | PCM16 24kHz mono | ✅ Compatible |
+| Context Window | 2M tokens | 128K tokens | N/A |
+
+**What LiteLLM Handles:**
+- ✅ Automatic URL routing to correct provider
+- ✅ Authentication headers (no `OpenAI-Beta` header for xAI)
+- ✅ WebSocket connection management
+- ✅ All other event types are compatible
+
+**What You Need to Handle:**
+- ⚠️ Initial event type difference (`conversation.created` vs `session.created`)
+
+**Tip:** Make your client compatible with both event types:
+```python
+# Handle both providers
+if event['type'] in ['session.created', 'conversation.created']:
+ print("Connection established")
+```
+
+## Related Documentation
+
+- [xAI Chat/Text Models](/docs/providers/xai)
+- [LiteLLM Realtime API Overview](/docs/realtime)
+- [xAI Official Documentation](https://docs.x.ai/docs)
+
+## Support
+
+For issues or questions:
+- [LiteLLM GitHub Issues](https://github.com/BerriAI/litellm/issues)
+- [xAI Documentation](https://docs.x.ai/docs)
diff --git a/docs/my-website/docs/proxy/admin_ui_sso.md b/docs/my-website/docs/proxy/admin_ui_sso.md
index 7b299429db7..37e45b50284 100644
--- a/docs/my-website/docs/proxy/admin_ui_sso.md
+++ b/docs/my-website/docs/proxy/admin_ui_sso.md
@@ -23,26 +23,75 @@ From v1.76.0, SSO is now Free for up to 5 users.
-1. Add Okta credentials to your .env
+#### Step 1: Create an OIDC Application in Okta
+
+In your Okta Admin Console, create a new **OIDC Web Application**. See [Okta's guide on creating OIDC app integrations](https://help.okta.com/en-us/content/topics/apps/apps_app_integration_wizard_oidc.htm) for detailed instructions.
+
+When configuring the application:
+- **Sign-in redirect URI**: `https:///sso/callback`
+- **Sign-out redirect URI** (optional): `https://`
+
+
+
+After creating the app, copy your **Client ID** and **Client Secret** from the application's General tab:
+
+
+
+#### Step 2: Assign Users to the Application
+
+Ensure users are assigned to the app in the **Assignments** tab. If Federation Broker Mode is enabled, you may need to disable it to assign users manually.
+
+#### Step 3: Configure Authorization Server Access Policy
+
+:::warning Important
+This step is required. Without an Access Policy for your app, users will get a `no_matching_policy` error when attempting to log in.
+:::
+
+1. Go to **Security** → **API**
+
+
+
+2. Select the **default** authorization server (or your custom one)
+
+
+
+3. Click on **Access Policies** tab, create a new policy assigned to your LiteLLM app
+4. Add a rule that allows the **Authorization Code** grant type
+
+
+
+See [Okta's Access Policy documentation](https://help.okta.com/en-us/content/topics/security/api-access-management/access-policies.htm) for more details.
+
+#### Step 4: Configure LiteLLM Environment Variables
```bash
-GENERIC_CLIENT_ID = ""
-GENERIC_CLIENT_SECRET = ""
-GENERIC_AUTHORIZATION_ENDPOINT = "/authorize" # https://dev-2kqkcd6lx6kdkuzt.us.auth0.com/authorize
-GENERIC_TOKEN_ENDPOINT = "/token" # https://dev-2kqkcd6lx6kdkuzt.us.auth0.com/oauth/token
-GENERIC_USERINFO_ENDPOINT = "/userinfo" # https://dev-2kqkcd6lx6kdkuzt.us.auth0.com/userinfo
-GENERIC_CLIENT_STATE = "random-string" # [OPTIONAL] REQUIRED BY OKTA, if not set random state value is generated
-GENERIC_SSO_HEADERS = "Content-Type=application/json, X-Custom-Header=custom-value" # [OPTIONAL] Comma-separated list of additional headers to add to the request - e.g. Content-Type=application/json, etc.
+GENERIC_CLIENT_ID=""
+GENERIC_CLIENT_SECRET=""
+GENERIC_AUTHORIZATION_ENDPOINT="https:///oauth2/default/v1/authorize"
+GENERIC_TOKEN_ENDPOINT="https:///oauth2/default/v1/token"
+GENERIC_USERINFO_ENDPOINT="https:///oauth2/default/v1/userinfo"
+GENERIC_CLIENT_STATE="random-string"
+PROXY_BASE_URL="https://"
```
-You can get your domain specific auth/token/userinfo endpoints at `/.well-known/openid-configuration`
+:::tip
+You can find all OAuth endpoints at `https:///.well-known/openid-configuration`
+:::
-2. Add proxy url as callback_url on Okta
+#### Step 5: Test the SSO Flow
-On Okta, add the 'callback_url' as `/sso/callback`
+1. Start your LiteLLM proxy
+2. Navigate to `https:///ui`
+3. Click the SSO login button
+4. Authenticate with Okta and verify you're redirected back to LiteLLM
+#### Troubleshooting
-
+| Error | Cause | Solution |
+|-------|-------|----------|
+| `redirect_uri` error | Redirect URI not configured | Add `/sso/callback` to Sign-in redirect URIs in Okta |
+| `access_denied` | User not assigned to app | Assign the user in the Assignments tab |
+| `no_matching_policy` | Missing Access Policy | Create an Access Policy in the Authorization Server (see Step 3) |
diff --git a/docs/my-website/docs/proxy/call_hooks.md b/docs/my-website/docs/proxy/call_hooks.md
index fe865f67e09..17354725fd5 100644
--- a/docs/my-website/docs/proxy/call_hooks.md
+++ b/docs/my-website/docs/proxy/call_hooks.md
@@ -19,6 +19,7 @@ import Image from '@theme/IdealImage';
| `async_post_call_success_hook` | Modify outgoing response (non-streaming) | After successful LLM API call, for non-streaming responses |
| `async_post_call_failure_hook` | Transform error responses sent to clients | After failed LLM API call |
| `async_post_call_streaming_hook` | Modify outgoing response (streaming) | After successful LLM API call, for streaming responses |
+| `async_post_call_response_headers_hook` | Inject custom HTTP response headers | After LLM API call (both success and failure) |
See a complete example with our [parallel request rate limiter](https://github.com/BerriAI/litellm/blob/main/litellm/proxy/hooks/parallel_request_limiter.py)
@@ -115,6 +116,18 @@ class MyCustomHandler(CustomLogger): # https://docs.litellm.ai/docs/observabilit
async for item in response:
yield item
+ async def async_post_call_response_headers_hook(
+ self,
+ data: dict,
+ user_api_key_dict: UserAPIKeyAuth,
+ response: Any,
+ request_headers: Optional[Dict[str, str]] = None,
+ ) -> Optional[Dict[str, str]]:
+ """
+ Inject custom headers into HTTP response (runs for both success and failure).
+ """
+ return {"x-custom-header": "custom-value"}
+
proxy_handler_instance = MyCustomHandler()
```
@@ -389,3 +402,31 @@ proxy_handler_instance = MyErrorTransformer()
```
**Result:** Clients receive `"Your prompt is too long..."` instead of `"ContextWindowExceededError: Prompt exceeds context window"`.
+
+## Advanced - Inject Custom HTTP Response Headers
+
+Use `async_post_call_response_headers_hook` to inject custom HTTP headers into responses. This hook runs for **both successful and failed** LLM API calls.
+
+```python
+from litellm.integrations.custom_logger import CustomLogger
+from litellm.proxy.proxy_server import UserAPIKeyAuth
+from typing import Any, Dict, Optional
+
+class CustomHeaderLogger(CustomLogger):
+ def __init__(self):
+ super().__init__()
+
+ async def async_post_call_response_headers_hook(
+ self,
+ data: dict,
+ user_api_key_dict: UserAPIKeyAuth,
+ response: Any,
+ request_headers: Optional[Dict[str, str]] = None,
+ ) -> Optional[Dict[str, str]]:
+ """
+ Inject custom headers into all responses (success and failure).
+ """
+ return {"x-custom-header": "custom-value"}
+
+proxy_handler_instance = CustomHeaderLogger()
+```
diff --git a/docs/my-website/docs/proxy/cli.md b/docs/my-website/docs/proxy/cli.md
index 9244f75b756..d3624000a32 100644
--- a/docs/my-website/docs/proxy/cli.md
+++ b/docs/my-website/docs/proxy/cli.md
@@ -1,7 +1,10 @@
# CLI Arguments
-Cli arguments, --host, --port, --num_workers
-## --host
+This page documents all command-line interface (CLI) arguments available for the LiteLLM proxy server.
+
+## Server Configuration
+
+### --host
- **Default:** `'0.0.0.0'`
- The host for the server to listen on.
- **Usage:**
@@ -14,7 +17,7 @@ Cli arguments, --host, --port, --num_workers
litellm
```
-## --port
+### --port
- **Default:** `4000`
- The port to bind the server to.
- **Usage:**
@@ -27,9 +30,9 @@ Cli arguments, --host, --port, --num_workers
litellm
```
-## --num_workers
- - **Default:** `1`
- - The number of uvicorn workers to spin up.
+### --num_workers
+ - **Default:** Number of logical CPUs in the system, or `4` if that cannot be determined
+ - The number of uvicorn / gunicorn workers to spin up.
- **Usage:**
```shell
litellm --num_workers 4
@@ -40,55 +43,273 @@ Cli arguments, --host, --port, --num_workers
litellm
```
-## --api_base
+### --config
+ - **Short form:** `-c`
- **Default:** `None`
- - The API base for the model litellm should call.
+ - Path to the proxy configuration file (e.g., config.yaml).
+ - **Usage:**
+ ```shell
+ litellm --config path/to/config.yaml
+ ```
+
+### --log_config
+ - **Default:** `None`
+ - **Type:** `str`
+ - Path to the logging configuration file for uvicorn.
+ - **Usage:**
+ ```shell
+ litellm --log_config path/to/log_config.conf
+ ```
+
+### --keepalive_timeout
+ - **Default:** `None`
+ - **Type:** `int`
+ - Set the uvicorn keepalive timeout in seconds (uvicorn timeout_keep_alive parameter).
+ - **Usage:**
+ ```shell
+ litellm --keepalive_timeout 30
+ ```
+ - **Usage - set Environment Variable:** `KEEPALIVE_TIMEOUT`
+ ```shell
+ export KEEPALIVE_TIMEOUT=30
+ litellm
+ ```
+
+### --max_requests_before_restart
+ - **Default:** `None`
+ - **Type:** `int`
+ - Restart worker after this many requests. This is useful for mitigating memory growth over time.
+ - For uvicorn: maps to `limit_max_requests`
+ - For gunicorn: maps to `max_requests`
+ - **Usage:**
+ ```shell
+ litellm --max_requests_before_restart 10000
+ ```
+ - **Usage - set Environment Variable:** `MAX_REQUESTS_BEFORE_RESTART`
+ ```shell
+ export MAX_REQUESTS_BEFORE_RESTART=10000
+ litellm
+ ```
+
+## Server Backend Options
+
+### --run_gunicorn
+ - **Default:** `False`
+ - **Type:** `bool` (Flag)
+ - Starts proxy via gunicorn instead of uvicorn. Better for managing multiple workers in production.
+ - **Usage:**
+ ```shell
+ litellm --run_gunicorn
+ ```
+
+### --run_hypercorn
+ - **Default:** `False`
+ - **Type:** `bool` (Flag)
+ - Starts proxy via hypercorn instead of uvicorn. Supports HTTP/2.
+ - **Usage:**
+ ```shell
+ litellm --run_hypercorn
+ ```
+
+### --skip_server_startup
+ - **Default:** `False`
+ - **Type:** `bool` (Flag)
+ - Skip starting the server after setup (useful for database migrations only).
+ - **Usage:**
+ ```shell
+ litellm --skip_server_startup
+ ```
+
+## SSL/TLS Configuration
+
+### --ssl_keyfile_path
+ - **Default:** `None`
+ - **Type:** `str`
+ - Path to the SSL keyfile. Use this when you want to provide SSL certificate when starting proxy.
+ - **Usage:**
+ ```shell
+ litellm --ssl_keyfile_path /path/to/key.pem --ssl_certfile_path /path/to/cert.pem
+ ```
+ - **Usage - set Environment Variable:** `SSL_KEYFILE_PATH`
+ ```shell
+ export SSL_KEYFILE_PATH=/path/to/key.pem
+ litellm
+ ```
+
+### --ssl_certfile_path
+ - **Default:** `None`
+ - **Type:** `str`
+ - Path to the SSL certfile. Use this when you want to provide SSL certificate when starting proxy.
+ - **Usage:**
+ ```shell
+ litellm --ssl_certfile_path /path/to/cert.pem --ssl_keyfile_path /path/to/key.pem
+ ```
+ - **Usage - set Environment Variable:** `SSL_CERTFILE_PATH`
+ ```shell
+ export SSL_CERTFILE_PATH=/path/to/cert.pem
+ litellm
+ ```
+
+### --ciphers
+ - **Default:** `None`
+ - **Type:** `str`
+ - Ciphers to use for the SSL setup. Only used with `--run_hypercorn`.
+ - **Usage:**
+ ```shell
+ litellm --run_hypercorn --ssl_keyfile_path /path/to/key.pem --ssl_certfile_path /path/to/cert.pem --ciphers "ECDHE+AESGCM"
+ ```
+
+## Model Configuration
+
+### --model or -m
+ - **Default:** `None`
+ - The model name to pass to LiteLLM.
+ - **Usage:**
+ ```shell
+ litellm --model gpt-3.5-turbo
+ ```
+
+### --alias
+ - **Default:** `None`
+ - An alias for the model, for user-friendly reference. Use this to give a litellm model name (e.g., "huggingface/codellama/CodeLlama-7b-Instruct-hf") a more user-friendly name ("codellama").
+ - **Usage:**
+ ```shell
+ litellm --alias my-gpt-model
+ ```
+
+### --api_base
+ - **Default:** `None`
+ - The API base for the model LiteLLM should call.
- **Usage:**
```shell
litellm --model huggingface/tinyllama --api_base https://k58ory32yinf1ly0.us-east-1.aws.endpoints.huggingface.cloud
```
-## --api_version
- - **Default:** `None`
+### --api_version
+ - **Default:** `2024-07-01-preview`
- For Azure services, specify the API version.
- **Usage:**
```shell
litellm --model azure/gpt-deployment --api_version 2023-08-01 --api_base https://"
```
-## --model or -m
+### --headers
- **Default:** `None`
- - The model name to pass to Litellm.
+ - Headers for the API call (as JSON string).
- **Usage:**
```shell
- litellm --model gpt-3.5-turbo
+ litellm --model my-model --headers '{"Authorization": "Bearer token"}'
```
-## --test
- - **Type:** `bool` (Flag)
- - Proxy chat completions URL to make a test request.
- - **Usage:**
- ```shell
- litellm --test
- ```
-
-## --health
- - **Type:** `bool` (Flag)
- - Runs a health check on all models in config.yaml
- - **Usage:**
- ```shell
- litellm --health
- ```
-
-## --alias
+### --add_key
- **Default:** `None`
- - An alias for the model, for user-friendly reference.
+ - Add a key to the model configuration.
- **Usage:**
```shell
- litellm --alias my-gpt-model
+ litellm --add_key my-api-key
```
-## --debug
+### --save
+ - **Type:** `bool` (Flag)
+ - Save the model-specific config.
+ - **Usage:**
+ ```shell
+ litellm --model gpt-3.5-turbo --save
+ ```
+
+## Model Parameters
+
+### --temperature
+ - **Default:** `None`
+ - **Type:** `float`
+ - Set the temperature for the model.
+ - **Usage:**
+ ```shell
+ litellm --temperature 0.7
+ ```
+
+### --max_tokens
+ - **Default:** `None`
+ - **Type:** `int`
+ - Set the maximum number of tokens for the model output.
+ - **Usage:**
+ ```shell
+ litellm --max_tokens 50
+ ```
+
+### --request_timeout
+ - **Default:** `None`
+ - **Type:** `int`
+ - Set the timeout in seconds for completion calls.
+ - **Usage:**
+ ```shell
+ litellm --request_timeout 300
+ ```
+
+### --max_budget
+ - **Default:** `None`
+ - **Type:** `float`
+ - Set max budget for API calls. Works for hosted models like OpenAI, TogetherAI, Anthropic, etc.
+ - **Usage:**
+ ```shell
+ litellm --max_budget 100.0
+ ```
+
+### --drop_params
+ - **Type:** `bool` (Flag)
+ - Drop any unmapped params.
+ - **Usage:**
+ ```shell
+ litellm --drop_params
+ ```
+
+### --add_function_to_prompt
+ - **Type:** `bool` (Flag)
+ - If a function passed but unsupported, pass it as a part of the prompt.
+ - **Usage:**
+ ```shell
+ litellm --add_function_to_prompt
+ ```
+
+## Database Configuration
+
+### --iam_token_db_auth
+ - **Default:** `False`
+ - **Type:** `bool` (Flag)
+ - Connects to an RDS database using IAM token authentication instead of a password. This is useful for AWS RDS instances that are configured to use IAM database authentication.
+ - When enabled, LiteLLM will generate an IAM authentication token to connect to the database.
+ - **Required Environment Variables:**
+ - `DATABASE_HOST` - The RDS database host
+ - `DATABASE_PORT` - The database port
+ - `DATABASE_USER` - The database user
+ - `DATABASE_NAME` - The database name
+ - `DATABASE_SCHEMA` (optional) - The database schema
+ - **Usage:**
+ ```shell
+ litellm --iam_token_db_auth
+ ```
+ - **Usage - set Environment Variable:** `IAM_TOKEN_DB_AUTH`
+ ```shell
+ export IAM_TOKEN_DB_AUTH=True
+ export DATABASE_HOST=mydb.us-east-1.rds.amazonaws.com
+ export DATABASE_PORT=5432
+ export DATABASE_USER=mydbuser
+ export DATABASE_NAME=mydb
+ litellm
+ ```
+
+### --use_prisma_db_push
+ - **Default:** `False`
+ - **Type:** `bool` (Flag)
+ - Use `prisma db push` instead of `prisma migrate` for database schema updates. This is useful when you want to quickly sync your database schema without creating migration files.
+ - **Usage:**
+ ```shell
+ litellm --use_prisma_db_push
+ ```
+
+## Debugging
+
+### --debug
- **Default:** `False`
- **Type:** `bool` (Flag)
- Enable debugging mode for the input.
@@ -102,10 +323,10 @@ Cli arguments, --host, --port, --num_workers
litellm
```
-## --detailed_debug
+### --detailed_debug
- **Default:** `False`
- **Type:** `bool` (Flag)
- - Enable debugging mode for the input.
+ - Enable detailed debugging mode to view verbose debug logs.
- **Usage:**
```shell
litellm --detailed_debug
@@ -116,80 +337,76 @@ Cli arguments, --host, --port, --num_workers
litellm
```
-#### --temperature
- - **Default:** `None`
- - **Type:** `float`
- - Set the temperature for the model.
- - **Usage:**
- ```shell
- litellm --temperature 0.7
- ```
-
-## --max_tokens
- - **Default:** `None`
- - **Type:** `int`
- - Set the maximum number of tokens for the model output.
- - **Usage:**
- ```shell
- litellm --max_tokens 50
- ```
-
-## --request_timeout
- - **Default:** `6000`
- - **Type:** `int`
- - Set the timeout in seconds for completion calls.
- - **Usage:**
- ```shell
- litellm --request_timeout 300
- ```
-
-## --drop_params
+### --local
+ - **Default:** `False`
- **Type:** `bool` (Flag)
- - Drop any unmapped params.
+ - For local debugging purposes.
- **Usage:**
```shell
- litellm --drop_params
+ litellm --local
```
-## --add_function_to_prompt
+## Testing & Health Checks
+
+### --test
- **Type:** `bool` (Flag)
- - If a function passed but unsupported, pass it as a part of the prompt.
+ - Proxy chat completions URL to make a test request to.
- **Usage:**
```shell
- litellm --add_function_to_prompt
+ litellm --test
```
-## --config
- - Configure Litellm by providing a configuration file path.
+### --test_async
+ - **Default:** `False`
+ - **Type:** `bool` (Flag)
+ - Calls async endpoints `/queue/requests` and `/queue/response`.
- **Usage:**
```shell
- litellm --config path/to/config.yaml
+ litellm --test_async
```
-## --telemetry
+### --num_requests
+ - **Default:** `10`
+ - **Type:** `int`
+ - Number of requests to hit async endpoint with (used with `--test_async`).
+ - **Usage:**
+ ```shell
+ litellm --test_async --num_requests 100
+ ```
+
+### --health
+ - **Type:** `bool` (Flag)
+ - Runs a health check on all models in config.yaml.
+ - **Usage:**
+ ```shell
+ litellm --health
+ ```
+
+## Other Options
+
+### --version
+ - **Short form:** `-v`
+ - **Type:** `bool` (Flag)
+ - Print LiteLLM version and exit.
+ - **Usage:**
+ ```shell
+ litellm --version
+ ```
+
+### --telemetry
- **Default:** `True`
- **Type:** `bool`
- - Help track usage of this feature.
+ - Help track usage of this feature. Turn off for privacy.
- **Usage:**
```shell
litellm --telemetry False
```
-
-## --log_config
- - **Default:** `None`
- - **Type:** `str`
- - Specify a log configuration file for uvicorn.
- - **Usage:**
- ```shell
- litellm --log_config path/to/log_config.conf
- ```
-
-## --skip_server_startup
+### --use_queue
- **Default:** `False`
- **Type:** `bool` (Flag)
- - Skip starting the server after setup (useful for DB migrations only).
+ - To use celery workers for async endpoints.
- **Usage:**
```shell
- litellm --skip_server_startup
- ```
\ No newline at end of file
+ litellm --use_queue
+ ```
diff --git a/docs/my-website/docs/proxy/cli_sso.md b/docs/my-website/docs/proxy/cli_sso.md
index cde6bf266d4..ad0f033f802 100644
--- a/docs/my-website/docs/proxy/cli_sso.md
+++ b/docs/my-website/docs/proxy/cli_sso.md
@@ -28,6 +28,37 @@ EXPERIMENTAL_UI_LOGIN="True" litellm --config config.yaml
:::
+### Configuration
+
+#### JWT Token Expiration
+
+By default, CLI authentication tokens expire after **24 hours**. You can customize this expiration time by setting the `LITELLM_CLI_JWT_EXPIRATION_HOURS` environment variable when starting your LiteLLM Proxy:
+
+```bash
+# Set CLI JWT tokens to expire after 48 hours
+export LITELLM_CLI_JWT_EXPIRATION_HOURS=48
+export EXPERIMENTAL_UI_LOGIN="True"
+litellm --config config.yaml
+```
+
+Or in a single command:
+
+```bash
+LITELLM_CLI_JWT_EXPIRATION_HOURS=48 EXPERIMENTAL_UI_LOGIN="True" litellm --config config.yaml
+```
+
+**Examples:**
+- `LITELLM_CLI_JWT_EXPIRATION_HOURS=12` - Tokens expire after 12 hours
+- `LITELLM_CLI_JWT_EXPIRATION_HOURS=168` - Tokens expire after 7 days (168 hours)
+- `LITELLM_CLI_JWT_EXPIRATION_HOURS=720` - Tokens expire after 30 days (720 hours)
+
+:::tip
+You can check your current token's age and expiration status using:
+```bash
+litellm-proxy whoami
+```
+:::
+
### Steps
1. **Install the CLI**
diff --git a/docs/my-website/docs/proxy/config_settings.md b/docs/my-website/docs/proxy/config_settings.md
index 89e1e2910e4..5cdae51f448 100644
--- a/docs/my-website/docs/proxy/config_settings.md
+++ b/docs/my-website/docs/proxy/config_settings.md
@@ -94,7 +94,7 @@ litellm_settings:
# /chat/completions, /completions, /embeddings, /audio/transcriptions
mode: default_off # if default_off, you need to opt in to caching on a per call basis
ttl: 600 # ttl for caching
- disable_copilot_system_to_assistant: False # If false (default), converts all 'system' role messages to 'assistant' for GitHub Copilot compatibility. Set to true to disable this behavior.
+ disable_copilot_system_to_assistant: False # DEPRECATED - GitHub Copilot API supports system prompts.
callback_settings:
otel:
@@ -197,7 +197,7 @@ router_settings:
| disable_add_transform_inline_image_block | boolean | For Fireworks AI models - if true, turns off the auto-add of `#transform=inline` to the url of the image_url, if the model is not a vision model. |
| disable_hf_tokenizer_download | boolean | If true, it defaults to using the openai tokenizer for all models (including huggingface models). |
| enable_json_schema_validation | boolean | If true, enables json schema validation for all requests. |
-| disable_copilot_system_to_assistant | boolean | If false (default), converts all 'system' role messages to 'assistant' for GitHub Copilot compatibility. Set to true to disable this behavior. Useful for tools (like Claude Code) that send system messages, which Copilot does not support. |
+| disable_copilot_system_to_assistant | boolean | **DEPRECATED** - GitHub Copilot API supports system prompts. |
### general_settings - Reference
@@ -321,6 +321,7 @@ router_settings:
| redis_host | string | The host address for the Redis server. **Only set this if you have multiple instances of LiteLLM Proxy and want current tpm/rpm tracking to be shared across them** |
| redis_password | string | The password for the Redis server. **Only set this if you have multiple instances of LiteLLM Proxy and want current tpm/rpm tracking to be shared across them** |
| redis_port | string | The port number for the Redis server. **Only set this if you have multiple instances of LiteLLM Proxy and want current tpm/rpm tracking to be shared across them**|
+| redis_db | int | The database number for the Redis server. **Only set this if you have multiple instances of LiteLLM Proxy and want current tpm/rpm tracking to be shared across them**|
| enable_pre_call_check | boolean | If true, checks if a call is within the model's context window before making the call. [More information here](reliability) |
| content_policy_fallbacks | array of objects | Specifies fallback models for content policy violations. [More information here](reliability) |
| fallbacks | array of objects | Specifies fallback models for all types of errors. [More information here](reliability) |
@@ -452,6 +453,8 @@ router_settings:
| BERRISPEND_ACCOUNT_ID | Account ID for BerriSpend service
| BRAINTRUST_API_KEY | API key for Braintrust integration
| BRAINTRUST_API_BASE | Base URL for Braintrust API. Default is https://api.braintrustdata.com/v1
+| BRAINTRUST_MOCK | Enable mock mode for Braintrust integration testing. When set to true, intercepts Braintrust API calls and returns mock responses without making actual network calls. Default is false
+| BRAINTRUST_MOCK_LATENCY_MS | Mock latency in milliseconds for Braintrust API calls when mock mode is enabled. Simulates network round-trip time. Default is 100ms
| CACHED_STREAMING_CHUNK_DELAY | Delay in seconds for cached streaming chunks. Default is 0.02
| CHATGPT_API_BASE | Base URL for ChatGPT API. Default is https://chatgpt.com/backend-api/codex
| CHATGPT_AUTH_FILE | Filename for ChatGPT authentication data. Default is "auth.json"
@@ -462,6 +465,7 @@ router_settings:
| CHATGPT_USER_AGENT_SUFFIX | Suffix to append to the ChatGPT user agent string
| CIRCLE_OIDC_TOKEN | OpenID Connect token for CircleCI
| CIRCLE_OIDC_TOKEN_V2 | Version 2 of the OpenID Connect token for CircleCI
+| CLI_JWT_EXPIRATION_HOURS | Expiration time in hours for CLI-generated JWT tokens. Default is 24 hours. Can also be set via LITELLM_CLI_JWT_EXPIRATION_HOURS
| CLOUDZERO_API_KEY | CloudZero API key for authentication
| CLOUDZERO_CONNECTION_ID | CloudZero connection ID for data submission
| CLOUDZERO_EXPORT_INTERVAL_MINUTES | Interval in minutes for CloudZero data export operations
@@ -504,12 +508,15 @@ router_settings:
| DD_AGENT_HOST | Hostname or IP of DataDog agent (e.g., "localhost"). When set, logs are sent to agent instead of direct API
| DD_AGENT_PORT | Port of DataDog agent for log intake. Default is 10518
| DD_API_KEY | API key for Datadog integration
+| DD_APP_KEY | Application key for Datadog Cost Management integration. Required along with DD_API_KEY for cost metrics
| DD_SITE | Site URL for Datadog (e.g., datadoghq.com)
| DD_SOURCE | Source identifier for Datadog logs
| DD_TRACER_STREAMING_CHUNK_YIELD_RESOURCE | Resource name for Datadog tracing of streaming chunk yields. Default is "streaming.chunk.yield"
| DD_ENV | Environment identifier for Datadog logs. Only supported for `datadog_llm_observability` callback
| DD_SERVICE | Service identifier for Datadog logs. Defaults to "litellm-server"
| DD_VERSION | Version identifier for Datadog logs. Defaults to "unknown"
+| DATADOG_MOCK | Enable mock mode for Datadog integration testing. When set to true, intercepts Datadog API calls and returns mock responses without making actual network calls. Default is false
+| DATADOG_MOCK_LATENCY_MS | Mock latency in milliseconds for Datadog API calls when mock mode is enabled. Simulates network round-trip time. Default is 100ms
| DEBUG_OTEL | Enable debug mode for OpenTelemetry
| DEFAULT_ALLOWED_FAILS | Maximum failures allowed before cooling down a model. Default is 3
| DEFAULT_A2A_AGENT_TIMEOUT | Default timeout in seconds for A2A (Agent-to-Agent) protocol requests. Default is 6000
@@ -538,6 +545,9 @@ router_settings:
| DEFAULT_MAX_TOKENS | Default maximum tokens for LLM calls. Default is 4096
| DEFAULT_MAX_TOKENS_FOR_TRITON | Default maximum tokens for Triton models. Default is 2000
| DEFAULT_MAX_REDIS_BATCH_CACHE_SIZE | Default maximum size for redis batch cache. Default is 1000
+| DEFAULT_MCP_SEMANTIC_FILTER_EMBEDDING_MODEL | Default embedding model for MCP semantic tool filtering. Default is "text-embedding-3-small"
+| DEFAULT_MCP_SEMANTIC_FILTER_SIMILARITY_THRESHOLD | Default similarity threshold for MCP semantic tool filtering. Default is 0.3
+| DEFAULT_MCP_SEMANTIC_FILTER_TOP_K | Default number of top results to return for MCP semantic tool filtering. Default is 10
| DEFAULT_MOCK_RESPONSE_COMPLETION_TOKEN_COUNT | Default token count for mock response completions. Default is 20
| DEFAULT_MOCK_RESPONSE_PROMPT_TOKEN_COUNT | Default token count for mock response prompts. Default is 10
| DEFAULT_MODEL_CREATED_AT_TIME | Default creation timestamp for models. Default is 1677610602
@@ -611,6 +621,8 @@ router_settings:
| GALILEO_USERNAME | Username for Galileo authentication
| GOOGLE_SECRET_MANAGER_PROJECT_ID | Project ID for Google Secret Manager
| GCS_BUCKET_NAME | Name of the Google Cloud Storage bucket
+| GCS_MOCK | Enable mock mode for GCS integration testing. When set to true, intercepts GCS API calls and returns mock responses without making actual network calls. Default is false
+| GCS_MOCK_LATENCY_MS | Mock latency in milliseconds for GCS API calls when mock mode is enabled. Simulates network round-trip time. Default is 150ms
| GCS_PATH_SERVICE_ACCOUNT | Path to the Google Cloud service account JSON file
| GCS_FLUSH_INTERVAL | Flush interval for GCS logging (in seconds). Specify how often you want a log to be sent to GCS. **Default is 20 seconds**
| GCS_BATCH_SIZE | Batch size for GCS logging. Specify after how many logs you want to flush to GCS. If `BATCH_SIZE` is set to 10, logs are flushed every 10 logs. **Default is 2048**
@@ -636,6 +648,10 @@ router_settings:
| GENERIC_USERINFO_ENDPOINT | Endpoint to fetch user information in generic OAuth
| GENERIC_LOGGER_ENDPOINT | Endpoint URL for the Generic Logger callback to send logs to
| GENERIC_LOGGER_HEADERS | JSON string of headers to include in Generic Logger callback requests
+| GENERIC_ROLE_MAPPINGS_DEFAULT_ROLE | Default LiteLLM role to assign when no role mapping matches in generic SSO. Used with GENERIC_ROLE_MAPPINGS_ROLES
+| GENERIC_ROLE_MAPPINGS_GROUP_CLAIM | The claim/attribute name in the SSO token that contains the user's groups. Used for role mapping
+| GENERIC_ROLE_MAPPINGS_ROLES | Python dict string mapping LiteLLM roles to SSO group names. Example: `{"proxy_admin": ["admin-group"], "internal_user": ["users"]}`
+| GENERIC_USER_ROLE_MAPPINGS | Alternative to GENERIC_ROLE_MAPPINGS_ROLES for configuring user role mappings from SSO
| GEMINI_API_BASE | Base URL for Gemini API. Default is https://generativelanguage.googleapis.com
| GALILEO_BASE_URL | Base URL for Galileo platform
| GALILEO_PASSWORD | Password for Galileo authentication
@@ -672,6 +688,8 @@ router_settings:
| HCP_VAULT_CERT_ROLE | Role for [Hashicorp Vault Secret Manager Auth](../secret.md#hashicorp-vault)
| HELICONE_API_KEY | API key for Helicone service
| HELICONE_API_BASE | Base URL for Helicone service, defaults to `https://api.helicone.ai`
+| HELICONE_MOCK | Enable mock mode for Helicone integration testing. When set to true, intercepts Helicone API calls and returns mock responses without making actual network calls. Default is false
+| HELICONE_MOCK_LATENCY_MS | Mock latency in milliseconds for Helicone API calls when mock mode is enabled. Simulates network round-trip time. Default is 100ms
| HOSTNAME | Hostname for the server, this will be [emitted to `datadog` logs](https://docs.litellm.ai/docs/proxy/logging#datadog)
| HOURS_IN_A_DAY | Hours in a day for calculation purposes. Default is 24
| HIDDENLAYER_API_BASE | Base URL for HiddenLayer API. Defaults to `https://api.hiddenlayer.ai`
@@ -697,6 +715,8 @@ router_settings:
| LANGFUSE_FLUSH_INTERVAL | Interval for flushing Langfuse logs
| LANGFUSE_TRACING_ENVIRONMENT | Environment for Langfuse tracing
| LANGFUSE_HOST | Host URL for Langfuse service
+| LANGFUSE_MOCK | Enable mock mode for Langfuse integration testing. When set to true, intercepts Langfuse API calls and returns mock responses without making actual network calls. Default is false
+| LANGFUSE_MOCK_LATENCY_MS | Mock latency in milliseconds for Langfuse API calls when mock mode is enabled. Simulates network round-trip time. Default is 100ms
| LANGFUSE_PUBLIC_KEY | Public key for Langfuse authentication
| LANGFUSE_RELEASE | Release version of Langfuse integration
| LANGFUSE_SECRET_KEY | Secret key for Langfuse authentication
@@ -708,6 +728,8 @@ router_settings:
| LANGSMITH_PROJECT | Project name for Langsmith integration
| LANGSMITH_SAMPLING_RATE | Sampling rate for Langsmith logging
| LANGSMITH_TENANT_ID | Tenant ID for Langsmith multi-tenant deployments
+| LANGSMITH_MOCK | Enable mock mode for Langsmith integration testing. When set to true, intercepts Langsmith API calls and returns mock responses without making actual network calls. Default is false
+| LANGSMITH_MOCK_LATENCY_MS | Mock latency in milliseconds for Langsmith API calls when mock mode is enabled. Simulates network round-trip time. Default is 100ms
| LANGTRACE_API_KEY | API key for Langtrace service
| LASSO_API_BASE | Base URL for Lasso API
| LASSO_API_KEY | API key for Lasso service
@@ -719,8 +741,10 @@ router_settings:
| LITERAL_API_URL | API URL for Literal service
| LITERAL_BATCH_SIZE | Batch size for Literal operations
| LITELLM_ANTHROPIC_DISABLE_URL_SUFFIX | Disable automatic URL suffix appending for Anthropic API base URLs. When set to `true`, prevents LiteLLM from automatically adding `/v1/messages` or `/v1/complete` to custom Anthropic API endpoints
+| LITELLM_CLI_JWT_EXPIRATION_HOURS | Expiration time in hours for CLI-generated JWT tokens. Default is 24 hours
| LITELLM_DD_AGENT_HOST | Hostname or IP of DataDog agent for LiteLLM-specific logging. When set, logs are sent to agent instead of direct API
| LITELLM_DD_AGENT_PORT | Port of DataDog agent for LiteLLM-specific log intake. Default is 10518
+| LITELLM_DD_LLM_OBS_PORT | Port for Datadog LLM Observability agent. Default is 8126
| LITELLM_DONT_SHOW_FEEDBACK_BOX | Flag to hide feedback box in LiteLLM UI
| LITELLM_DROP_PARAMS | Parameters to drop in LiteLLM requests
| LITELLM_MODIFY_PARAMS | Parameters to modify in LiteLLM requests
@@ -781,6 +805,7 @@ router_settings:
| MAXIMUM_TRACEBACK_LINES_TO_LOG | Maximum number of lines to log in traceback in LiteLLM Logs UI. Default is 100
| MAX_RETRY_DELAY | Maximum delay in seconds for retrying requests. Default is 8.0
| MAX_LANGFUSE_INITIALIZED_CLIENTS | Maximum number of Langfuse clients to initialize on proxy. Default is 50. This is set since langfuse initializes 1 thread everytime a client is initialized. We've had an incident in the past where we reached 100% cpu utilization because Langfuse was initialized several times.
+| MAX_MCP_SEMANTIC_FILTER_TOOLS_HEADER_LENGTH | Maximum header length for MCP semantic filter tools. Default is 150
| MIN_NON_ZERO_TEMPERATURE | Minimum non-zero temperature value. Default is 0.0001
| MINIMUM_PROMPT_CACHE_TOKEN_COUNT | Minimum token count for caching a prompt. Default is 1024
| MISTRAL_API_BASE | Base URL for Mistral API. Default is https://api.mistral.ai
@@ -816,6 +841,7 @@ router_settings:
| OPENMETER_EVENT_TYPE | Type of events sent to OpenMeter
| ONYX_API_BASE | Base URL for Onyx Security AI Guard service (defaults to https://ai-guard.onyx.security)
| ONYX_API_KEY | API key for Onyx Security AI Guard service
+| ONYX_TIMEOUT | Timeout in seconds for Onyx Guard server requests. Default is 10
| OTEL_ENDPOINT | OpenTelemetry endpoint for traces
| OTEL_EXPORTER_OTLP_ENDPOINT | OpenTelemetry endpoint for traces
| OTEL_ENVIRONMENT_NAME | Environment name for OpenTelemetry
@@ -839,6 +865,8 @@ router_settings:
| POD_NAME | Pod name for the server, this will be [emitted to `datadog` logs](https://docs.litellm.ai/docs/proxy/logging#datadog) as `POD_NAME`
| POSTHOG_API_KEY | API key for PostHog analytics integration
| POSTHOG_API_URL | Base URL for PostHog API (defaults to https://us.i.posthog.com)
+| POSTHOG_MOCK | Enable mock mode for PostHog integration testing. When set to true, intercepts PostHog API calls and returns mock responses without making actual network calls. Default is false
+| POSTHOG_MOCK_LATENCY_MS | Mock latency in milliseconds for PostHog API calls when mock mode is enabled. Simulates network round-trip time. Default is 100ms
| PREDIBASE_API_BASE | Base URL for Predibase API
| PRESIDIO_ANALYZER_API_BASE | Base URL for Presidio Analyzer service
| PRESIDIO_ANONYMIZER_API_BASE | Base URL for Presidio Anonymizer service
@@ -876,6 +904,8 @@ router_settings:
| ROUTER_MAX_FALLBACKS | Maximum number of fallbacks for router. Default is 5
| RUNWAYML_DEFAULT_API_VERSION | Default API version for RunwayML service. Default is "2024-11-06"
| RUNWAYML_POLLING_TIMEOUT | Timeout in seconds for RunwayML image generation polling. Default is 600 (10 minutes)
+| S3_VECTORS_DEFAULT_DIMENSION | Default vector dimension for S3 Vectors RAG ingestion. Default is 1024
+| S3_VECTORS_DEFAULT_DISTANCE_METRIC | Default distance metric for S3 Vectors RAG ingestion. Options: "cosine", "euclidean". Default is "cosine"
| SECRET_MANAGER_REFRESH_INTERVAL | Refresh interval in seconds for secret manager. Default is 86400 (24 hours)
| SEPARATE_HEALTH_APP | If set to '1', runs health endpoints on a separate ASGI app and port. Default: '0'.
| SEPARATE_HEALTH_PORT | Port for the separate health endpoints app. Only used if SEPARATE_HEALTH_APP=1. Default: 4001.
diff --git a/docs/my-website/docs/proxy/custom_pricing.md b/docs/my-website/docs/proxy/custom_pricing.md
index 8f4a4c450f5..b61da85bb1d 100644
--- a/docs/my-website/docs/proxy/custom_pricing.md
+++ b/docs/my-website/docs/proxy/custom_pricing.md
@@ -9,6 +9,7 @@ LiteLLM provides flexible cost tracking and pricing customization for all LLM pr
- **Custom Pricing** - Override default model costs or set pricing for custom models
- **Cost Per Token** - Track costs based on input/output tokens (most common)
- **Cost Per Second** - Track costs based on runtime (e.g., Sagemaker)
+- **Zero-Cost Models** - Bypass budget checks for free/on-premises models by setting costs to 0
- **[Provider Discounts](./provider_discounts.md)** - Apply percentage-based discounts to specific providers
- **[Provider Margins](./provider_margins.md)** - Add fees/margins to LLM costs for internal billing
- **Base Model Mapping** - Ensure accurate cost tracking for Azure deployments
@@ -106,6 +107,51 @@ There are other keys you can use to specify costs for different scenarios and mo
These keys evolve based on how new models handle multimodality. The latest version can be found at [https://github.com/BerriAI/litellm/blob/main/model_prices_and_context_window.json](https://github.com/BerriAI/litellm/blob/main/model_prices_and_context_window.json).
+## Zero-Cost Models (Bypass Budget Checks)
+
+**Use Case**: You have on-premises or free models that should be accessible even when users exceed their budget limits.
+
+**Solution** ✅: Set both `input_cost_per_token` and `output_cost_per_token` to `0` (explicitly) to bypass all budget checks for that model.
+
+:::info
+
+When a model is configured with zero cost, LiteLLM will automatically skip ALL budget checks (user, team, team member, end-user, organization, and global proxy budget) for requests to that model.
+
+**Important**: Both costs must be **explicitly set to 0**. If costs are `null` or undefined, the model will be treated as having cost and budget checks will apply.
+
+:::
+
+### Configuration Example
+
+```yaml
+model_list:
+ # On-premises model - free to use
+ - model_name: on-prem-llama
+ litellm_params:
+ model: ollama/llama3
+ api_base: http://localhost:11434
+ model_info:
+ input_cost_per_token: 0 # 👈 Explicitly set to 0
+ output_cost_per_token: 0 # 👈 Explicitly set to 0
+
+ # Paid cloud model - budget checks apply
+ - model_name: gpt-4
+ litellm_params:
+ model: gpt-4
+ api_key: os.environ/OPENAI_API_KEY
+ # No model_info - uses default pricing from cost map
+```
+
+### Behavior
+
+With the above configuration:
+
+- **User over budget** → Can still use `on-prem-llama` ✅, but blocked from `gpt-4` ❌
+- **Team over budget** → Can still use `on-prem-llama` ✅, but blocked from `gpt-4` ❌
+- **End-user over budget** → Can still use `on-prem-llama` ✅, but blocked from `gpt-4` ❌
+
+This ensures your free/on-premises models remain accessible regardless of budget constraints, while paid models are still properly governed.
+
## Set 'base_model' for Cost Tracking (e.g. Azure deployments)
**Problem**: Azure returns `gpt-4` in the response when `azure/gpt-4-1106-preview` is used. This leads to inaccurate cost tracking
diff --git a/docs/my-website/docs/proxy/deploy.md b/docs/my-website/docs/proxy/deploy.md
index 7393e73ba87..0761e0e9fa8 100644
--- a/docs/my-website/docs/proxy/deploy.md
+++ b/docs/my-website/docs/proxy/deploy.md
@@ -200,6 +200,7 @@ Example `requirements.txt`
```shell
litellm[proxy]==1.57.3 # Specify the litellm version you want to use
+litellm-enterprise
prometheus_client
langfuse
prisma
diff --git a/docs/my-website/docs/proxy/embedding.md b/docs/my-website/docs/proxy/embedding.md
index 2adaaa24735..0e7c2d55c44 100644
--- a/docs/my-website/docs/proxy/embedding.md
+++ b/docs/my-website/docs/proxy/embedding.md
@@ -6,6 +6,16 @@ import TabItem from '@theme/TabItem';
See supported Embedding Providers & Models [here](https://docs.litellm.ai/docs/embedding/supported_embedding)
+## Supported Input Formats
+
+The `/v1/embeddings` endpoint follows the [OpenAI embeddings API specification](https://platform.openai.com/docs/api-reference/embeddings/create). The following input formats are supported:
+
+| Format | Example |
+|--------|---------|
+| String | `"input": "Hello"` |
+| Array of strings | `"input": ["Hello", "World"]` |
+| Array of tokens (integers) | `"input": [1234, 5678, 9012]` |
+| Array of token arrays | `"input": [[1234, 5678], [9012, 3456]]` |
## Quick start
Here's how to route between GPT-J embedding (sagemaker endpoint), Amazon Titan embedding (Bedrock) and Azure OpenAI embedding on the proxy server:
diff --git a/docs/my-website/docs/proxy/guardrails/custom_code_guardrail.md b/docs/my-website/docs/proxy/guardrails/custom_code_guardrail.md
new file mode 100644
index 00000000000..8cbc247ae5e
--- /dev/null
+++ b/docs/my-website/docs/proxy/guardrails/custom_code_guardrail.md
@@ -0,0 +1,332 @@
+import Tabs from '@theme/Tabs';
+import TabItem from '@theme/TabItem';
+
+# Custom Code Guardrail
+
+Write custom guardrail logic using Python-like code that runs in a sandboxed environment.
+
+## Quick Start
+
+### 1. Define the guardrail in config
+
+```yaml
+model_list:
+ - model_name: gpt-4
+ litellm_params:
+ model: gpt-4
+ api_key: os.environ/OPENAI_API_KEY
+
+guardrails:
+ - guardrail_name: block-ssn
+ litellm_params:
+ guardrail: custom_code
+ mode: pre_call
+ custom_code: |
+ def apply_guardrail(inputs, request_data, input_type):
+ for text in inputs["texts"]:
+ if regex_match(text, r"\d{3}-\d{2}-\d{4}"):
+ return block("SSN detected")
+ return allow()
+```
+
+### 2. Start proxy
+
+```bash
+litellm --config config.yaml
+```
+
+### 3. Test
+
+```bash
+curl -X POST http://localhost:4000/chat/completions \
+ -H "Authorization: Bearer sk-1234" \
+ -H "Content-Type: application/json" \
+ -d '{
+ "model": "gpt-4",
+ "messages": [{"role": "user", "content": "My SSN is 123-45-6789"}],
+ "guardrails": ["block-ssn"]
+ }'
+```
+
+## Configuration
+
+| Parameter | Type | Required | Description |
+|-----------|------|----------|-------------|
+| `guardrail` | string | ✅ | Must be `custom_code` |
+| `mode` | string | ✅ | When to run: `pre_call`, `post_call`, `during_call` |
+| `custom_code` | string | ✅ | Python-like code with `apply_guardrail` function |
+| `default_on` | bool | ❌ | Run on all requests (default: `false`) |
+
+## Writing Custom Code
+
+### Function Signature
+
+Your code must define an `apply_guardrail` function. It can be either sync or async:
+
+```python
+# Sync version
+def apply_guardrail(inputs, request_data, input_type):
+ # inputs: see table below
+ # request_data: {"model": "...", "user_id": "...", "team_id": "...", "metadata": {...}}
+ # input_type: "request" or "response"
+
+ return allow() # or block() or modify()
+
+# Async version (recommended when using HTTP primitives)
+async def apply_guardrail(inputs, request_data, input_type):
+ response = await http_post("https://api.example.com/check", body={"text": inputs["texts"][0]})
+ if response["success"] and response["body"].get("flagged"):
+ return block("Content flagged")
+ return allow()
+```
+
+### `inputs` Parameter
+
+| Field | Type | Description |
+|-------|------|-------------|
+| `texts` | `List[str]` | Extracted text from the request/response |
+| `images` | `List[str]` | Extracted images (for image guardrails) |
+| `tools` | `List[dict]` | Tools sent to the LLM |
+| `tool_calls` | `List[dict]` | Tool calls returned from the LLM |
+| `structured_messages` | `List[dict]` | Full messages with role info (system/user/assistant) |
+| `model` | `str` | The model being used |
+
+### `request_data` Parameter
+
+| Field | Type | Description |
+|-------|------|-------------|
+| `model` | `str` | Model name |
+| `user_id` | `str` | User ID from API key |
+| `team_id` | `str` | Team ID from API key |
+| `end_user_id` | `str` | End user ID |
+| `metadata` | `dict` | Request metadata |
+
+### Return Values
+
+| Function | Description |
+|----------|-------------|
+| `allow()` | Let request/response through |
+| `block(reason)` | Reject with message |
+| `modify(texts=[], images=[], tool_calls=[])` | Transform content |
+
+## Built-in Primitives
+
+### Regex
+
+| Function | Description |
+|----------|-------------|
+| `regex_match(text, pattern)` | Returns `True` if pattern found |
+| `regex_replace(text, pattern, replacement)` | Replace all matches |
+| `regex_find_all(text, pattern)` | Return list of matches |
+
+### JSON
+
+| Function | Description |
+|----------|-------------|
+| `json_parse(text)` | Parse JSON string, returns `None` on error |
+| `json_stringify(obj)` | Convert to JSON string |
+| `json_schema_valid(obj, schema)` | Validate against JSON schema |
+
+### URL
+
+| Function | Description |
+|----------|-------------|
+| `extract_urls(text)` | Extract all URLs from text |
+| `is_valid_url(url)` | Check if URL is valid |
+| `all_urls_valid(text)` | Check all URLs in text are valid |
+
+### Code Detection
+
+| Function | Description |
+|----------|-------------|
+| `detect_code(text)` | Returns `True` if code detected |
+| `detect_code_languages(text)` | Returns list of detected languages |
+| `contains_code_language(text, ["sql", "python"])` | Check for specific languages |
+
+### Text Utilities
+
+| Function | Description |
+|----------|-------------|
+| `contains(text, substring)` | Check if substring exists |
+| `contains_any(text, [substr1, substr2])` | Check if any substring exists |
+| `word_count(text)` | Count words |
+| `char_count(text)` | Count characters |
+| `lower(text)` / `upper(text)` / `trim(text)` | String transforms |
+
+### HTTP Requests (Async)
+
+Make async HTTP requests to external APIs for additional validation or content moderation.
+
+| Function | Description |
+|----------|-------------|
+| `await http_request(url, method, headers, body, timeout)` | General async HTTP request |
+| `await http_get(url, headers, timeout)` | Async GET request |
+| `await http_post(url, body, headers, timeout)` | Async POST request |
+
+**Response format:**
+```python
+{
+ "status_code": 200, # HTTP status code
+ "body": {...}, # Response body (parsed JSON or string)
+ "headers": {...}, # Response headers
+ "success": True, # True if status code is 2xx
+ "error": None # Error message if request failed
+}
+```
+
+**Note:** When using HTTP primitives, define your function as `async def apply_guardrail(...)` for non-blocking execution.
+
+## Examples
+
+### Block PII (SSN)
+
+```python
+def apply_guardrail(inputs, request_data, input_type):
+ for text in inputs["texts"]:
+ if regex_match(text, r"\d{3}-\d{2}-\d{4}"):
+ return block("SSN detected")
+ return allow()
+```
+
+### Redact Email Addresses
+
+```python
+def apply_guardrail(inputs, request_data, input_type):
+ pattern = r"[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}"
+ modified = []
+ for text in inputs["texts"]:
+ modified.append(regex_replace(text, pattern, "[EMAIL REDACTED]"))
+ return modify(texts=modified)
+```
+
+### Block SQL Injection
+
+```python
+def apply_guardrail(inputs, request_data, input_type):
+ if input_type != "request":
+ return allow()
+ for text in inputs["texts"]:
+ if contains_code_language(text, ["sql"]):
+ return block("SQL code not allowed")
+ return allow()
+```
+
+### Validate JSON Response
+
+```python
+def apply_guardrail(inputs, request_data, input_type):
+ if input_type != "response":
+ return allow()
+
+ schema = {
+ "type": "object",
+ "required": ["name", "value"]
+ }
+
+ for text in inputs["texts"]:
+ obj = json_parse(text)
+ if obj is None:
+ return block("Invalid JSON response")
+ if not json_schema_valid(obj, schema):
+ return block("Response missing required fields")
+ return allow()
+```
+
+### Check URLs in Response
+
+```python
+def apply_guardrail(inputs, request_data, input_type):
+ if input_type != "response":
+ return allow()
+ for text in inputs["texts"]:
+ if not all_urls_valid(text):
+ return block("Response contains invalid URLs")
+ return allow()
+```
+
+### Call External Moderation API (Async)
+
+```python
+async def apply_guardrail(inputs, request_data, input_type):
+ # Call an external moderation API
+ for text in inputs["texts"]:
+ response = await http_post(
+ "https://api.example.com/moderate",
+ body={"text": text, "user_id": request_data["user_id"]},
+ headers={"Authorization": "Bearer YOUR_API_KEY"},
+ timeout=10
+ )
+
+ if not response["success"]:
+ # API call failed - decide whether to allow or block
+ return allow()
+
+ if response["body"].get("flagged"):
+ return block(response["body"].get("reason", "Content flagged"))
+
+ return allow()
+```
+
+### Combine Multiple Checks
+
+```python
+def apply_guardrail(inputs, request_data, input_type):
+ modified = []
+
+ for text in inputs["texts"]:
+ # Redact SSN
+ text = regex_replace(text, r"\d{3}-\d{2}-\d{4}", "[SSN]")
+ # Redact credit cards
+ text = regex_replace(text, r"\d{16}", "[CARD]")
+ modified.append(text)
+
+ # Block SQL in requests
+ if input_type == "request":
+ for text in inputs["texts"]:
+ if contains_code_language(text, ["sql"]):
+ return block("SQL injection blocked")
+
+ return modify(texts=modified)
+```
+
+## Sandbox Restrictions
+
+Custom code runs in a restricted environment:
+
+- ❌ No `import` statements
+- ❌ No file I/O
+- ❌ No `exec()` or `eval()`
+- ✅ HTTP requests via built-in `http_request`, `http_get`, `http_post` primitives
+- ✅ Only LiteLLM-provided primitives available
+
+## Per-Request Usage
+
+Enable guardrail per request:
+
+```bash
+curl -X POST http://localhost:4000/chat/completions \
+ -H "Authorization: Bearer sk-1234" \
+ -H "Content-Type: application/json" \
+ -d '{
+ "model": "gpt-4",
+ "messages": [{"role": "user", "content": "Hello"}],
+ "guardrails": ["block-ssn"]
+ }'
+```
+
+## Default On
+
+Run guardrail on all requests:
+
+```yaml
+litellm_settings:
+ guardrails:
+ - guardrail_name: block-ssn
+ litellm_params:
+ guardrail: custom_code
+ mode: pre_call
+ default_on: true
+ custom_code: |
+ def apply_guardrail(inputs, request_data, input_type):
+ ...
+```
diff --git a/docs/my-website/docs/proxy/guardrails/grayswan.md b/docs/my-website/docs/proxy/guardrails/grayswan.md
index d6efaf15504..6c0ccbc293d 100644
--- a/docs/my-website/docs/proxy/guardrails/grayswan.md
+++ b/docs/my-website/docs/proxy/guardrails/grayswan.md
@@ -13,20 +13,26 @@ Cygnal returns a `violation` score between `0` and `1` (higher means more likely
### 1. Obtain Credentials
-1. Create a Gray Swan account and generate a Cygnal API key.
+1. Log in to our Gray Swan platform and generate a Cygnal API key.
+
+ For existing customers, you should already have access to our [platform](https://platform.grayswan.ai).
+
+ For new users, please register at this [page](https://hubs.ly/Q03-sX1J0) and we are more than happy to give you an onboarding!
+
+
2. Configure environment variables for the LiteLLM proxy host:
-```bash
-export GRAYSWAN_API_KEY="your-grayswan-key"
-export GRAYSWAN_API_BASE="https://api.grayswan.ai"
-```
+ ```bash
+ export GRAYSWAN_API_KEY="your-grayswan-key"
+ export GRAYSWAN_API_BASE="https://api.grayswan.ai"
+ ```
### 2. Configure `config.yaml`
-Add a guardrail entry that references the Gray Swan integration. Below is a balanced example that monitors both input and output but only blocks once the violation score reaches the configured threshold.
+Add a guardrail entry that references the Gray Swan integration. Below is our recommmended settings.
```yaml
-model_list:
+model_list: # this part is a standard litellm configuration for reference
- model_name: openai/gpt-4.1-mini
litellm_params:
model: openai/gpt-4.1-mini
@@ -40,13 +46,14 @@ guardrails:
api_key: os.environ/GRAYSWAN_API_KEY
api_base: os.environ/GRAYSWAN_API_BASE # optional
optional_params:
- on_flagged_action: monitor # or "block"
+ on_flagged_action: passthrough # or "block" or "monitor"
violation_threshold: 0.5 # score >= threshold is flagged
reasoning_mode: hybrid # off | hybrid | thinking
- categories:
- safety: "Detect jailbreaks and policy violations"
- policy_id: "your-cygnal-policy-id"
+ policy_id: "your-cygnal-policy-id" # Optional: Your Cygnal policy ID. Defaults to a content safety policy if empty.
+ streaming_end_of_stream_only: true # For streaming API, only send the assembled message to Cygnal (post_call only). Defaults to false.
default_on: true
+ guardrail_timeout: 30 # Defaults to 30 seconds. Change accordingly.
+ fail_open: true # Defaults to true; set to false to propagate guardrail errors.
general_settings:
master_key: "your-litellm-master-key"
@@ -65,13 +72,13 @@ litellm --config config.yaml --port 4000
## Choosing Guardrail Modes
-Gray Swan can run during `pre_call`, `during_call`, and `post_call` stages. Combine modes based on your latency and coverage requirements.
+Gray Swan can run during `pre_call`, `during_call`, and `post_call` stages. Combine modes based on your latency and coverage requirements.
| Mode | When it Runs | Protects | Typical Use Case |
|--------------|-------------------|-----------------------|------------------|
| `pre_call` | Before LLM call | User input only | Block prompt injection before it reaches the model |
| `during_call`| Parallel to call | User input only | Low-latency monitoring without blocking |
-| `post_call` | After response | Full conversation | Scan output for policy violations, leaked secrets, or IPI |
+| `post_call` | After response | Model Outputs | Scan output for policy violations, leaked secrets, or IPI |
When using `during_call` with `on_flagged_action: block` or `on_flagged_action: passthrough`:
@@ -81,87 +88,110 @@ When using `during_call` with `on_flagged_action: block` or `on_flagged_action:
- The guardrail exception prevents the response from reaching the user, but **does not cancel the running LLM task**
- This means you pay full LLM costs while returning an error/passthrough message to the user
-**Recommendation:** For cost-sensitive applications, use `pre_call` and `post_call` instead of `during_call` for blocking or passthrough modes. Reserve `during_call` for `monitor` mode where you want low-latency logging without impacting the user experience.
+**Recommendation:** Use `pre_call` and `post_call` instead of `during_call` for `passthrough` (or `block`) `on_flagged_action` (see our recommended configuration above). Reserve `during_call` for `monitor` mode ONLY when you want low-latency logging without impacting the user experience.
-
-
+---
-```yaml
-guardrails:
- - guardrail_name: "cygnal-monitor-only"
- litellm_params:
- guardrail: grayswan
- mode: "during_call"
- api_key: os.environ/GRAYSWAN_API_KEY
- optional_params:
- on_flagged_action: monitor
- violation_threshold: 0.6
- default_on: true
+## Work with Claude Code
+
+Follow the official litellm [guide](https://docs.litellm.ai/docs/tutorials/claude_responses_api) on setting up Claude Code with litellm, with the guardrail part mentioned above added to your litellm configuration. Cygnal natively supports coding agent policies defense. Define your own policy or use the provided coding policies on the platform. The example config we show above is also the recommended setup for Claude Code (with the `policy_id` replaced with an appropriate one).
+
+---
+
+## Per-request overrides via `extra_body`
+
+You can override parts of the Gray Swan guardrail configuration on a per-request basis by passing `litellm_metadata.guardrails[*].grayswan.extra_body`.
+
+`extra_body` is merged into the Cygnal request body and takes precedence over specific fields from `config.yaml`, which are `policy_id`, `violation_threshold`, and `reasoning_mode`.
+
+If you include a `metadata` field inside `extra_body`, it is forwarded to the Cygnal API as-is under the request body's `metadata` field.
+
+Example:
+
+```bash
+curl -X POST "http://0.0.0.0:4000/v1/messages?beta=true" \
+ -H "Authorization: Bearer token" \
+ -H "Content-Type: application/json" \
+ -d '{
+ "model": "openrouter/anthropic/claude-sonnet-4.5",
+ "messages": [{"role": "user", "content": "hello"}],
+ "litellm_metadata": {
+ "guardrails": [
+ {
+ "cygnal-monitor": {
+ "extra_body": {
+ "policy_id": "specific policy id you want to use",
+ "metadata": {
+ "user": "health-check"
+ }
+ }
+ }
+ }
+ ]
+ }
+ }'
```
-Best for visibility without blocking. Alerts are logged via LiteLLM’s standard logging callbacks.
+OpenAI client:
-
-
+```python
+from openai import OpenAI
-```yaml
-guardrails:
- - guardrail_name: "cygnal-block-input"
- litellm_params:
- guardrail: grayswan
- mode: "pre_call"
- api_key: os.environ/GRAYSWAN_API_KEY
- optional_params:
- on_flagged_action: block
- violation_threshold: 0.4
- categories:
- pii: "Detect sensitive data"
- default_on: true
+client = OpenAI(api_key="anything", base_url="http://0.0.0.0:4000")
+
+resp = client.responses.create(
+ model="openrouter/anthropic/claude-sonnet-4.5",
+ input="hello",
+ extra_body={
+ "litellm_metadata": {
+ "guardrails": [
+ {
+ "cygnal-monitor": {
+ "extra_body": {
+ "policy_id": "69038214e5cdb6befc5e991e",
+ "metadata": {"trace_id": "trace-123"},
+ }
+ }
+ }
+ ]
+ }
+ },
+)
```
-Stops malicious or sensitive prompts before any tokens are generated.
+Anthropic client:
-
-
+```python
+from anthropic import Anthropic
-```yaml
-guardrails:
- - guardrail_name: "cygnal-full-coverage"
- litellm_params:
- guardrail: grayswan
- mode: [pre_call, post_call]
- api_key: os.environ/GRAYSWAN_API_KEY
- optional_params:
- on_flagged_action: block
- violation_threshold: 0.5
- reasoning_mode: thinking
- policy_id: "policy-id-from-grayswan"
- default_on: true
+client = Anthropic(api_key="anything", base_url="http://0.0.0.0:4000")
+
+resp = client.messages.create(
+ model="openrouter/anthropic/claude-sonnet-4.5",
+ max_tokens=256,
+ messages=[{"role": "user", "content": "hello"}],
+ extra_body={
+ "litellm_metadata": {
+ "guardrails": [
+ {
+ "cygnal-monitor": {
+ "extra_body": {
+ "policy_id": "69038214e5cdb6befc5e991e",
+ "metadata": {"trace_id": "trace-123"},
+ }
+ }
+ }
+ ]
+ }
+ },
+)
```
-Provides the strongest enforcement by inspecting both prompts and responses.
+Notes:
-
-
-
-```yaml
-guardrails:
- - guardrail_name: "cygnal-passthrough"
- litellm_params:
- guardrail: grayswan
- mode: [pre_call, post_call]
- api_key: os.environ/GRAYSWAN_API_KEY
- optional_params:
- on_flagged_action: passthrough
- violation_threshold: 0.5
- default_on: true
-```
-
-Allows requests to proceed without raising a 400 error when content is flagged. Instead of blocking, the model response content is replaced with a detailed violation message including violation score, violated rules, and detection flags (mutation, IPI). **Supported Response Formats:** OpenAI chat/text completions, Anthropic Messages API. Other response types (embeddings, images, etc.) will log a warning and return unchanged.
-
-
-
+- The guardrail name (for example, `cygnal-monitor`) must match the `guardrail_name` in `config.yaml`.
+- Per-request guardrail overrides may require a premium license, depending on your proxy settings.
---
@@ -170,9 +200,14 @@ Allows requests to proceed without raising a 400 error when content is flagged.
| Parameter | Type | Description |
|---------------------------------------|-----------------|-------------|
| `api_key` | string | Gray Swan Cygnal API key. Reads from `GRAYSWAN_API_KEY` if omitted. |
+| `api_base` | string | Override for the Gray Swan API base URL. Defaults to `https://api.grayswan.ai` or `GRAYSWAN_API_BASE`. |
| `mode` | string or list | Guardrail stages (`pre_call`, `during_call`, `post_call`). |
| `optional_params.on_flagged_action` | string | `monitor` (log only), `block` (raise `HTTPException`), or `passthrough` (replace response content with violation message, no 400 error). |
-| `.optional_params.violation_threshold`| number (0-1) | Scores at or above this value are considered violations. |
+| `optional_params.violation_threshold` | number (0-1) | Scores at or above this value are considered violations. |
| `optional_params.reasoning_mode` | string | `off`, `hybrid`, or `thinking`. Enables Cygnal's reasoning capabilities. |
| `optional_params.categories` | object | Map of custom category names to descriptions. |
| `optional_params.policy_id` | string | Gray Swan policy identifier. |
+| `guardrail_timeout` | number | Timeout in seconds for the Cygnal request. Defaults to 30. |
+| `fail_open` | boolean | If true, errors contacting Cygnal are logged and the request proceeds; if false, errors propagate. Defaults to treu. |
+| `streaming_end_of_stream_only` | boolean | For streaming `post_call`, only send the final assembled response to Cygnal. Defaults to false. |
+| `default_on` | boolean | Run the guardrail on every request by default. |
diff --git a/docs/my-website/docs/proxy/guardrails/guardrail_policies.md b/docs/my-website/docs/proxy/guardrails/guardrail_policies.md
new file mode 100644
index 00000000000..56be11c85a7
--- /dev/null
+++ b/docs/my-website/docs/proxy/guardrails/guardrail_policies.md
@@ -0,0 +1,283 @@
+# [Beta] Guardrail Policies
+
+Use policies to group guardrails and control which ones run for specific teams, keys, or models.
+
+## Why use policies?
+
+- Enable/disable specific guardrails for teams, keys, or models
+- Group guardrails into a single policy
+- Inherit from existing policies and override what you need
+
+## Quick Start
+
+```yaml showLineNumbers title="config.yaml"
+model_list:
+ - model_name: gpt-4
+ litellm_params:
+ model: openai/gpt-4
+
+# 1. Define your guardrails
+guardrails:
+ - guardrail_name: pii_masking
+ litellm_params:
+ guardrail: presidio
+ mode: pre_call
+
+ - guardrail_name: prompt_injection
+ litellm_params:
+ guardrail: lakera
+ mode: pre_call
+ api_key: os.environ/LAKERA_API_KEY
+
+# 2. Create a policy
+policies:
+ my-policy:
+ guardrails:
+ add:
+ - pii_masking
+ - prompt_injection
+
+# 3. Attach the policy
+policy_attachments:
+ - policy: my-policy
+ scope: "*" # apply to all requests
+```
+
+Response headers show what ran:
+
+```
+x-litellm-applied-policies: my-policy
+x-litellm-applied-guardrails: pii_masking,prompt_injection
+```
+
+## Add guardrails for a specific team
+
+:::info
+✨ Enterprise only feature for team/key-based policy attachments. [Get a free trial](https://www.litellm.ai/enterprise#trial)
+:::
+
+You have a global baseline, but want to add extra guardrails for a specific team.
+
+```yaml showLineNumbers title="config.yaml"
+policies:
+ global-baseline:
+ guardrails:
+ add:
+ - pii_masking
+
+ finance-team-policy:
+ inherit: global-baseline
+ guardrails:
+ add:
+ - strict_compliance_check
+ - audit_logger
+
+policy_attachments:
+ - policy: global-baseline
+ scope: "*"
+
+ - policy: finance-team-policy
+ teams:
+ - finance # team alias from /team/new
+```
+
+Now the `finance` team gets `pii_masking` + `strict_compliance_check` + `audit_logger`, while everyone else just gets `pii_masking`.
+
+## Remove guardrails for a specific team
+
+:::info
+✨ Enterprise only feature for team/key-based policy attachments. [Get a free trial](https://www.litellm.ai/enterprise#trial)
+:::
+
+You have guardrails running globally, but want to disable some for a specific team (e.g., internal testing).
+
+```yaml showLineNumbers title="config.yaml"
+policies:
+ global-baseline:
+ guardrails:
+ add:
+ - pii_masking
+ - prompt_injection
+
+ internal-team-policy:
+ inherit: global-baseline
+ guardrails:
+ remove:
+ - pii_masking # don't need PII masking for internal testing
+
+policy_attachments:
+ - policy: global-baseline
+ scope: "*"
+
+ - policy: internal-team-policy
+ teams:
+ - internal-testing # team alias from /team/new
+```
+
+Now the `internal-testing` team only gets `prompt_injection`, while everyone else gets both guardrails.
+
+## Inheritance
+
+Start with a base policy and build on it:
+
+```yaml showLineNumbers title="config.yaml"
+policies:
+ base:
+ guardrails:
+ add:
+ - pii_masking
+ - toxicity_filter
+
+ strict:
+ inherit: base
+ guardrails:
+ add:
+ - prompt_injection
+
+ relaxed:
+ inherit: base
+ guardrails:
+ remove:
+ - toxicity_filter
+```
+
+What you get:
+- `base` → `[pii_masking, toxicity_filter]`
+- `strict` → `[pii_masking, toxicity_filter, prompt_injection]`
+- `relaxed` → `[pii_masking]`
+
+## Model Conditions
+
+Run guardrails only for specific models:
+
+```yaml showLineNumbers title="config.yaml"
+policies:
+ gpt4-safety:
+ guardrails:
+ add:
+ - strict_content_filter
+ condition:
+ model: "gpt-4.*" # regex - matches gpt-4, gpt-4-turbo, gpt-4o
+
+ bedrock-compliance:
+ guardrails:
+ add:
+ - audit_logger
+ condition:
+ model: # exact match list
+ - bedrock/claude-3
+ - bedrock/claude-2
+```
+
+## Attachments
+
+Policies don't do anything until you attach them. Attachments tell LiteLLM *where* to apply each policy.
+
+**Global** - runs on every request:
+
+```yaml showLineNumbers title="config.yaml"
+policy_attachments:
+ - policy: default
+ scope: "*"
+```
+
+**Team-specific** (uses team alias from `/team/new`):
+
+```yaml showLineNumbers title="config.yaml"
+policy_attachments:
+ - policy: hipaa-compliance
+ teams:
+ - healthcare-team # team alias
+ - medical-research # team alias
+```
+
+**Key-specific** (uses key alias from `/key/generate`, wildcards supported):
+
+```yaml showLineNumbers title="config.yaml"
+policy_attachments:
+ - policy: internal-testing
+ keys:
+ - "dev-*" # key alias pattern
+ - "test-*" # key alias pattern
+```
+
+## Config Reference
+
+### `policies`
+
+```yaml
+policies:
+ :
+ description: ...
+ inherit: ...
+ guardrails:
+ add: [...]
+ remove: [...]
+ condition:
+ model: ...
+```
+
+| Field | Type | Description |
+|-------|------|-------------|
+| `description` | `string` | Optional. What this policy does. |
+| `inherit` | `string` | Optional. Parent policy to inherit guardrails from. |
+| `guardrails.add` | `list[string]` | Guardrails to enable. |
+| `guardrails.remove` | `list[string]` | Guardrails to disable (useful with inheritance). |
+| `condition.model` | `string` or `list[string]` | Optional. Only apply when model matches. Supports regex. |
+
+### `policy_attachments`
+
+```yaml
+policy_attachments:
+ - policy: ...
+ scope: ...
+ teams: [...]
+ keys: [...]
+```
+
+| Field | Type | Description |
+|-------|------|-------------|
+| `policy` | `string` | **Required.** Name of the policy to attach. |
+| `scope` | `string` | Use `"*"` to apply globally. |
+| `teams` | `list[string]` | Team aliases (from `/team/new`). |
+| `keys` | `list[string]` | Key aliases (from `/key/generate`). Supports `*` wildcard. |
+
+### Response Headers
+
+| Header | Description |
+|--------|-------------|
+| `x-litellm-applied-policies` | Policies that matched this request |
+| `x-litellm-applied-guardrails` | Guardrails that actually ran |
+
+## How it works
+
+Example config:
+
+```yaml showLineNumbers title="config.yaml"
+policies:
+ base:
+ guardrails:
+ add: [pii_masking]
+
+ finance-policy:
+ inherit: base
+ guardrails:
+ add: [audit_logger]
+
+policy_attachments:
+ - policy: base
+ scope: "*"
+ - policy: finance-policy
+ teams: [finance]
+```
+
+```mermaid
+flowchart TD
+ A["Request with team_alias='finance'"] --> B["Matches policies: base, finance-policy"]
+ B --> C["Resolves guardrails: pii_masking, audit_logger"]
+```
+
+1. Request comes in with `team_alias='finance'`
+2. Matches `base` (via `scope: "*"`) and `finance-policy` (via `teams: [finance]`)
+3. Resolves guardrails: `base` adds `pii_masking`, `finance-policy` inherits and adds `audit_logger`
+4. Final guardrails: `pii_masking`, `audit_logger`
diff --git a/docs/my-website/docs/proxy/guardrails/onyx_security.md b/docs/my-website/docs/proxy/guardrails/onyx_security.md
index 85b0ba9f830..d240902eb52 100644
--- a/docs/my-website/docs/proxy/guardrails/onyx_security.md
+++ b/docs/my-website/docs/proxy/guardrails/onyx_security.md
@@ -128,6 +128,7 @@ guardrails:
mode: ["pre_call", "post_call", "during_call"] # Run at multiple stages
api_key: os.environ/ONYX_API_KEY
api_base: os.environ/ONYX_API_BASE
+ timeout: 10.0 # Optional, defaults to 10 seconds
```
### Required Parameters
@@ -137,6 +138,7 @@ guardrails:
### Optional Parameters
- **`api_base`**: Onyx API base URL (defaults to `https://ai-guard.onyx.security`)
+- **`timeout`**: Request timeout in seconds (defaults to `10.0`)
## Environment Variables
@@ -145,4 +147,5 @@ You can set these environment variables instead of hardcoding values in your con
```shell
export ONYX_API_KEY="your-api-key-here"
export ONYX_API_BASE="https://ai-guard.onyx.security" # Optional
+export ONYX_TIMEOUT=10 # Optional, timeout in seconds
```
diff --git a/docs/my-website/docs/proxy/guardrails/quick_start.md b/docs/my-website/docs/proxy/guardrails/quick_start.md
index 4a8dc4e6fe4..ddb215fcb66 100644
--- a/docs/my-website/docs/proxy/guardrails/quick_start.md
+++ b/docs/my-website/docs/proxy/guardrails/quick_start.md
@@ -203,8 +203,12 @@ Your response headers will include `x-litellm-applied-guardrails` with the guard
x-litellm-applied-guardrails: aporia-pre-guard
```
+### Guardrail Policies
-
+Need more control? Use [Guardrail Policies](./guardrail_policies.md) to:
+- Group guardrails into reusable policies
+- Enable/disable guardrails for specific teams, keys, or models
+- Inherit from existing policies and override specific guardrails
## **Using Guardrails Client Side**
@@ -401,14 +405,10 @@ curl --location 'http://0.0.0.0:4000/chat/completions' \
## **Proxy Admin Controls**
-### ✨ Monitoring Guardrails
+### Monitoring Guardrails
Monitor which guardrails were executed and whether they passed or failed. e.g. guardrail going rogue and failing requests we don't intend to fail
-:::info
-
-✨ This is an Enterprise only feature [Get a free trial](https://www.litellm.ai/enterprise#trial)
-
:::
#### Setup
diff --git a/docs/my-website/docs/proxy/keys_teams_router_settings.md b/docs/my-website/docs/proxy/keys_teams_router_settings.md
new file mode 100644
index 00000000000..ec59e8f271b
--- /dev/null
+++ b/docs/my-website/docs/proxy/keys_teams_router_settings.md
@@ -0,0 +1,150 @@
+import Image from '@theme/IdealImage';
+
+# UI - Router Settings for Keys and Teams
+
+Configure router settings at the key and team level to achieve granular control over routing behavior, fallbacks, retries, and other router configurations. This enables you to customize routing behavior for specific keys or teams without affecting global settings.
+
+## Overview
+
+Router Settings for Keys and Teams allows you to configure router behavior at different levels of granularity. Previously, router settings could only be configured globally, applying the same routing strategy, fallbacks, timeouts, and retry policies to all requests across your entire proxy instance.
+
+With key-level and team-level router settings, you can now:
+
+- **Customize routing strategies** per key or team (e.g., use `least-busy` for high-priority keys, `latency-based-routing` for others)
+- **Configure different fallback chains** for different keys or teams
+- **Set key-specific or team-specific timeouts** and retry policies
+- **Apply different reliability settings** (cooldowns, allowed failures) per key or team
+- **Override global settings** when needed for specific use cases
+
+
+
+## Summary
+
+Router settings follow a **hierarchical resolution order**: **Keys > Teams > Global**. When a request is made:
+
+1. **Key-level settings** are checked first. If router settings are configured for the API key being used, those settings are applied.
+2. **Team-level settings** are checked next. If the key belongs to a team and that team has router settings configured, those settings are used (unless key-level settings exist).
+3. **Global settings** are used as the final fallback. If neither key nor team settings are found, the global router settings from your proxy configuration are applied.
+
+This hierarchical approach ensures that the most specific settings take precedence, allowing you to fine-tune routing behavior for individual keys or teams while maintaining sensible defaults at the global level.
+
+## How Router Settings Resolution Works
+
+Router settings are resolved in the following priority order:
+
+### Resolution Order: Key > Team > Global
+
+1. **Key-level router settings** (highest priority)
+ - Applied when router settings are configured directly on an API key
+ - Takes precedence over all other settings
+ - Useful for individual key customization
+
+2. **Team-level router settings** (medium priority)
+ - Applied when the API key belongs to a team with router settings configured
+ - Only used if no key-level settings exist
+ - Useful for applying consistent settings across multiple keys in a team
+
+3. **Global router settings** (lowest priority)
+ - Applied from your proxy configuration file or database
+ - Used as the default when no key or team settings are found
+ - Previously, this was the only option available
+
+## How to Configure Router Settings
+
+### Configuring Router Settings for Keys
+
+Follow these steps to configure router settings for an API key:
+
+1. Navigate to [http://localhost:4000/ui/?login=success](http://localhost:4000/ui/?login=success)
+
+
+
+2. Click "+ Create New Key" (or edit an existing key)
+
+
+
+3. Click "Optional Settings"
+
+
+
+4. Click "Router Settings"
+
+
+
+5. Configure your desired router settings. For example, click "Fallbacks" to configure fallback models:
+
+
+
+6. Click "Select a model to begin configuring fallbacks" and configure your fallback chain:
+
+
+
+### Configuring Router Settings for Teams
+
+Follow these steps to configure router settings for a team:
+
+1. Navigate to [http://localhost:4000/ui/?login=success](http://localhost:4000/ui/?login=success)
+
+
+
+2. Click "Teams"
+
+
+
+3. Click "+ Create New Team" (or edit an existing team)
+
+
+
+4. Click "Router Settings"
+
+
+
+5. Configure your desired router settings. For example, click "Fallbacks" to configure fallback models:
+
+
+
+6. Click "Select a model to begin configuring fallbacks" and configure your fallback chain:
+
+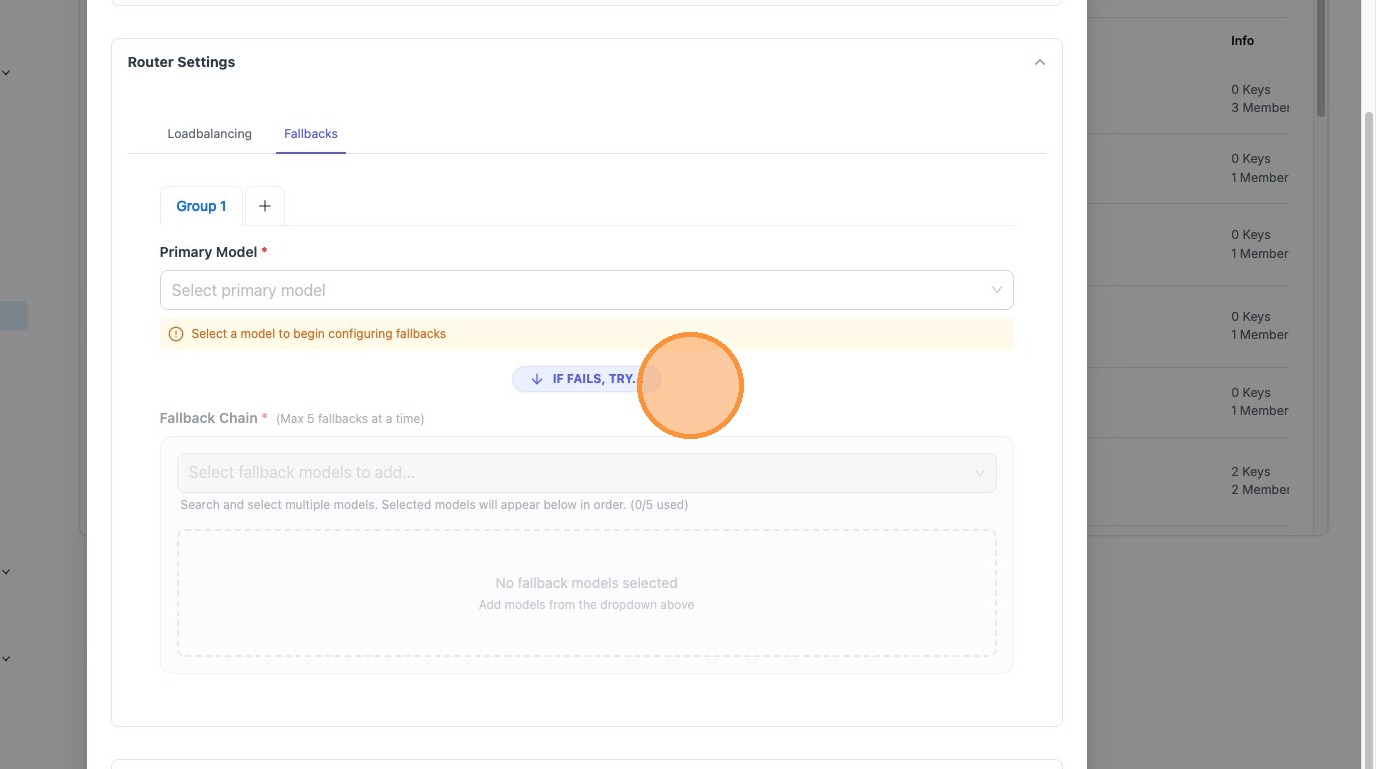
+
+## Use Cases
+
+### Different Routing Strategies per Key
+
+Configure different routing strategies for different use cases:
+
+- **High-priority production keys**: Use `latency-based-routing` for optimal performance
+- **Development keys**: Use `simple-shuffle` for simplicity
+- **Cost-sensitive keys**: Use `cost-based-routing` to minimize expenses
+
+### Team-Level Consistency
+
+Apply consistent router settings across all keys in a team:
+
+- Set team-wide fallback chains for reliability
+- Configure team-specific timeout policies
+- Apply uniform retry policies across team members
+
+### Override Global Settings
+
+Override global settings for specific scenarios:
+
+- Production keys may need stricter timeout policies than development
+- Certain teams may require different fallback models
+- Individual keys may need custom retry policies for specific use cases
+
+### Gradual Rollout
+
+Test new router settings on specific keys or teams before applying globally:
+
+- Configure new routing strategies on a test key first
+- Validate fallback chains on a small team before global rollout
+- A/B test different timeout values across different keys
+
+## Related Features
+
+- [Router Settings Reference](./config_settings.md#router_settings---reference) - Complete reference of all router settings
+- [Load Balancing](./load_balancing.md) - Learn about routing strategies and load balancing
+- [Reliability](./reliability.md) - Configure fallbacks, retries, and error handling
+- [Keys](./keys.md) - Manage API keys and their settings
+- [Teams](./teams.md) - Organize keys into teams
diff --git a/docs/my-website/docs/proxy/litellm_managed_files.md b/docs/my-website/docs/proxy/litellm_managed_files.md
index 7aba173f35b..6272180bd40 100644
--- a/docs/my-website/docs/proxy/litellm_managed_files.md
+++ b/docs/my-website/docs/proxy/litellm_managed_files.md
@@ -11,7 +11,7 @@ import Image from '@theme/IdealImage';
This is a free LiteLLM Enterprise feature.
-Available via the `litellm[proxy]` package or any `litellm` docker image.
+Available via the `litellm` docker image. If you are using the pip package, you must install [`litellm-enterprise`](https://pypi.org/project/litellm-enterprise/).
:::
diff --git a/docs/my-website/docs/proxy/load_balancing.md b/docs/my-website/docs/proxy/load_balancing.md
index 42f6ef1aa51..186307d6498 100644
--- a/docs/my-website/docs/proxy/load_balancing.md
+++ b/docs/my-website/docs/proxy/load_balancing.md
@@ -69,6 +69,67 @@ router_settings:
redis_port: 1992
```
+## Enforce Model Rate Limits
+
+Strictly enforce RPM/TPM limits set on deployments. When limits are exceeded, requests are blocked **before** reaching the LLM provider with a `429 Too Many Requests` error.
+
+:::info
+By default, `rpm` and `tpm` values are only used for **routing decisions** (picking deployments with capacity). With `enforce_model_rate_limits`, they become **hard limits**.
+:::
+
+### Quick Start
+
+```yaml
+model_list:
+ - model_name: gpt-4
+ litellm_params:
+ model: openai/gpt-4
+ api_key: os.environ/OPENAI_API_KEY
+ rpm: 60 # 60 requests per minute
+ tpm: 90000 # 90k tokens per minute
+
+router_settings:
+ optional_pre_call_checks:
+ - enforce_model_rate_limits # 👈 Enables strict enforcement
+```
+
+### How It Works
+
+| Limit Type | Enforcement | Accuracy |
+|------------|-------------|----------|
+| **RPM** | Hard limit - blocked at exact threshold | 100% accurate |
+| **TPM** | Best-effort - may slightly exceed | Blocked when already over limit |
+
+**Why TPM is best-effort:** Token count is unknown until the LLM responds. TPM is checked before each request (blocks if already over), and tracked after (adds actual tokens used).
+
+### Error Response
+
+```json
+{
+ "error": {
+ "message": "Model rate limit exceeded. RPM limit=60, current usage=60",
+ "type": "rate_limit_error",
+ "code": 429
+ }
+}
+```
+
+Response includes `retry-after: 60` header.
+
+### Multi-Instance Deployment
+
+For multiple LiteLLM proxy instances, add Redis to share rate limit state:
+
+```yaml
+router_settings:
+ optional_pre_call_checks:
+ - enforce_model_rate_limits
+ redis_host: redis.example.com
+ redis_port: 6379
+ redis_password: your-password
+```
+
+
:::info
Detailed information about [routing strategies can be found here](../routing)
:::
diff --git a/docs/my-website/docs/proxy/prometheus.md b/docs/my-website/docs/proxy/prometheus.md
index cd2b3b68f37..93a0675f097 100644
--- a/docs/my-website/docs/proxy/prometheus.md
+++ b/docs/my-website/docs/proxy/prometheus.md
@@ -121,8 +121,8 @@ Use this to track overall LiteLLM Proxy usage.
| Metric Name | Description |
|----------------------|--------------------------------------|
-| `litellm_proxy_failed_requests_metric` | Total number of failed responses from proxy - the client did not get a success response from litellm proxy. Labels: `"end_user", "hashed_api_key", "api_key_alias", "requested_model", "team", "team_alias", "user", "exception_status", "exception_class", "route"` |
-| `litellm_proxy_total_requests_metric` | Total number of requests made to the proxy server - track number of client side requests. Labels: `"end_user", "hashed_api_key", "api_key_alias", "requested_model", "team", "team_alias", "user", "status_code", "user_email", "route"` |
+| `litellm_proxy_failed_requests_metric` | Total number of failed responses from proxy - the client did not get a success response from litellm proxy. Labels: `"end_user", "hashed_api_key", "api_key_alias", "requested_model", "team", "team_alias", "user", "user_email", "exception_status", "exception_class", "route", "model_id"` |
+| `litellm_proxy_total_requests_metric` | Total number of requests made to the proxy server - track number of client side requests. Labels: `"end_user", "hashed_api_key", "api_key_alias", "requested_model", "team", "team_alias", "user", "status_code", "user_email", "route", "model_id"` |
### Callback Logging Metrics
@@ -130,7 +130,12 @@ Monitor failures while shipping logs to downstream callbacks like `s3_v3` cold s
| Metric Name | Description |
|----------------------|--------------------------------------|
-| `litellm_callback_logging_failures_metric` | Total number of failed attempts to emit logs to a configured callback. Labels: `"callback_name"`. Use this to alert on callback delivery issues such as repeated failures when writing to `s3_v3`. |
+| `litellm_callback_logging_failures_metric` | Total number of failed attempts to emit logs to a configured callback. Labels: `"callback_name"`. Use this to alert on callback delivery issues such as repeated failures when writing to `s3_v3`, `langfuse`, or `langfuse_otel` and other otel providers |
+
+**Supported Callbacks:**
+- `S3Logger` - S3 v2 cold storage failures
+- `langfuse` - Langfuse logging failures
+- `otel` - OpenTelemetry logging failures
## LLM Provider Metrics
@@ -191,10 +196,10 @@ Use this for LLM API Error monitoring and tracking remaining rate limits and tok
| Metric Name | Description |
|----------------------|--------------------------------------|
-| `litellm_request_total_latency_metric` | Total latency (seconds) for a request to LiteLLM Proxy Server - tracked for labels "end_user", "hashed_api_key", "api_key_alias", "requested_model", "team", "team_alias", "user", "model" |
+| `litellm_request_total_latency_metric` | Total latency (seconds) for a request to LiteLLM Proxy Server - tracked for labels "end_user", "hashed_api_key", "api_key_alias", "requested_model", "team", "team_alias", "user", "model", "model_id" |
| `litellm_overhead_latency_metric` | Latency overhead (seconds) added by LiteLLM processing - tracked for labels "model_group", "api_provider", "api_base", "litellm_model_name", "hashed_api_key", "api_key_alias" |
| `litellm_llm_api_latency_metric` | Latency (seconds) for just the LLM API call - tracked for labels "model", "hashed_api_key", "api_key_alias", "team", "team_alias", "requested_model", "end_user", "user" |
-| `litellm_llm_api_time_to_first_token_metric` | Time to first token for LLM API call - tracked for labels `model`, `hashed_api_key`, `api_key_alias`, `team`, `team_alias` [Note: only emitted for streaming requests] |
+| `litellm_llm_api_time_to_first_token_metric` | Time to first token for LLM API call - tracked for labels `model`, `hashed_api_key`, `api_key_alias`, `team`, `team_alias`, `requested_model`, `end_user`, `user`, `model_id` [Note: only emitted for streaming requests] |
## Tracking `end_user` on Prometheus
diff --git a/docs/my-website/docs/proxy/request_tags.md b/docs/my-website/docs/proxy/request_tags.md
new file mode 100644
index 00000000000..c78c48229b4
--- /dev/null
+++ b/docs/my-website/docs/proxy/request_tags.md
@@ -0,0 +1,58 @@
+# Request Tags for Spend Tracking
+
+Add tags to model deployments to track spend by environment, AWS account, or any custom label.
+
+Tags appear in the `request_tags` field of LiteLLM spend logs.
+
+## Config Setup
+
+Set tags on model deployments in `config.yaml`:
+
+```yaml title="config.yaml"
+model_list:
+ - model_name: gpt-4
+ litellm_params:
+ model: azure/gpt-4-prod
+ api_key: os.environ/AZURE_PROD_API_KEY
+ api_base: https://prod.openai.azure.com/
+ tags: ["AWS_IAM_PROD"] # 👈 Tag for production
+
+ - model_name: gpt-4-dev
+ litellm_params:
+ model: azure/gpt-4-dev
+ api_key: os.environ/AZURE_DEV_API_KEY
+ api_base: https://dev.openai.azure.com/
+ tags: ["AWS_IAM_DEV"] # 👈 Tag for development
+```
+
+## Make Request
+
+Requests just specify the model - tags are automatically applied:
+
+```bash
+curl -X POST 'http://0.0.0.0:4000/chat/completions' \
+ -H 'Authorization: Bearer sk-1234' \
+ -H 'Content-Type: application/json' \
+ -d '{
+ "model": "gpt-4",
+ "messages": [{"role": "user", "content": "Hello"}]
+ }'
+```
+
+## Spend Logs
+
+The tag from the model config appears in `LiteLLM_SpendLogs`:
+
+```json
+{
+ "request_id": "chatcmpl-abc123",
+ "request_tags": ["AWS_IAM_PROD"],
+ "spend": 0.002,
+ "model": "gpt-4"
+}
+```
+
+## Related
+
+- [Spend Tracking Overview](cost_tracking.md)
+- [Tag Budgets](tag_budgets.md) - Set budget limits per tag
diff --git a/docs/my-website/docs/proxy/ui/page_visibility.md b/docs/my-website/docs/proxy/ui/page_visibility.md
new file mode 100644
index 00000000000..06b06f33219
--- /dev/null
+++ b/docs/my-website/docs/proxy/ui/page_visibility.md
@@ -0,0 +1,121 @@
+import Image from '@theme/IdealImage';
+
+# Control Page Visibility for Internal Users
+
+Configure which navigation tabs and pages are visible to internal users (non-admin developers) in the LiteLLM UI.
+
+Use this feature to simplify the UI and control which pages your internal users/developers can see when signing in.
+
+## Overview
+
+By default, all pages accessible to internal users are visible in the navigation sidebar. The page visibility control allows admins to restrict which pages internal users can see, creating a more focused and streamlined experience.
+
+
+## Configure Page Visibility
+
+### 1. Navigate to Settings
+
+Click the **Settings** icon in the sidebar.
+
+
+
+### 2. Go to Admin Settings
+
+Click **Admin Settings** from the settings menu.
+
+
+
+### 3. Select UI Settings
+
+Click **UI Settings** to access the page visibility controls.
+
+
+
+### 4. Open Page Visibility Configuration
+
+Click **Configure Page Visibility** to expand the configuration panel.
+
+
+
+### 5. Select Pages to Make Visible
+
+Check the boxes for the pages you want internal users to see. Pages are organized by category for easy navigation.
+
+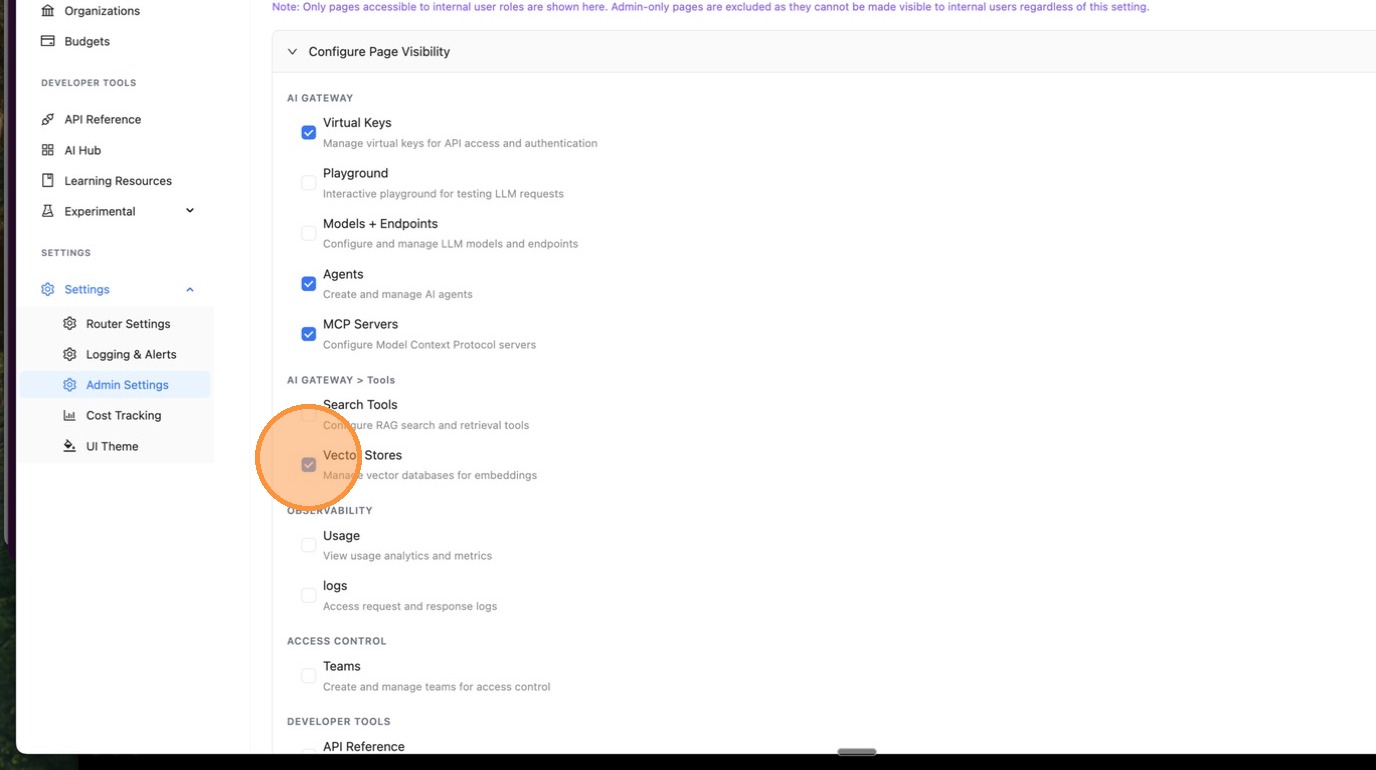
+
+**Available pages include:**
+- Virtual Keys
+- Playground
+- Models + Endpoints
+- Agents
+- MCP Servers
+- Search Tools
+- Vector Stores
+- Logs
+- Teams
+- Organizations
+- Usage
+- Budgets
+- And more...
+
+### 6. Save Your Configuration
+
+Click **Save Page Visibility Settings** to apply the changes.
+
+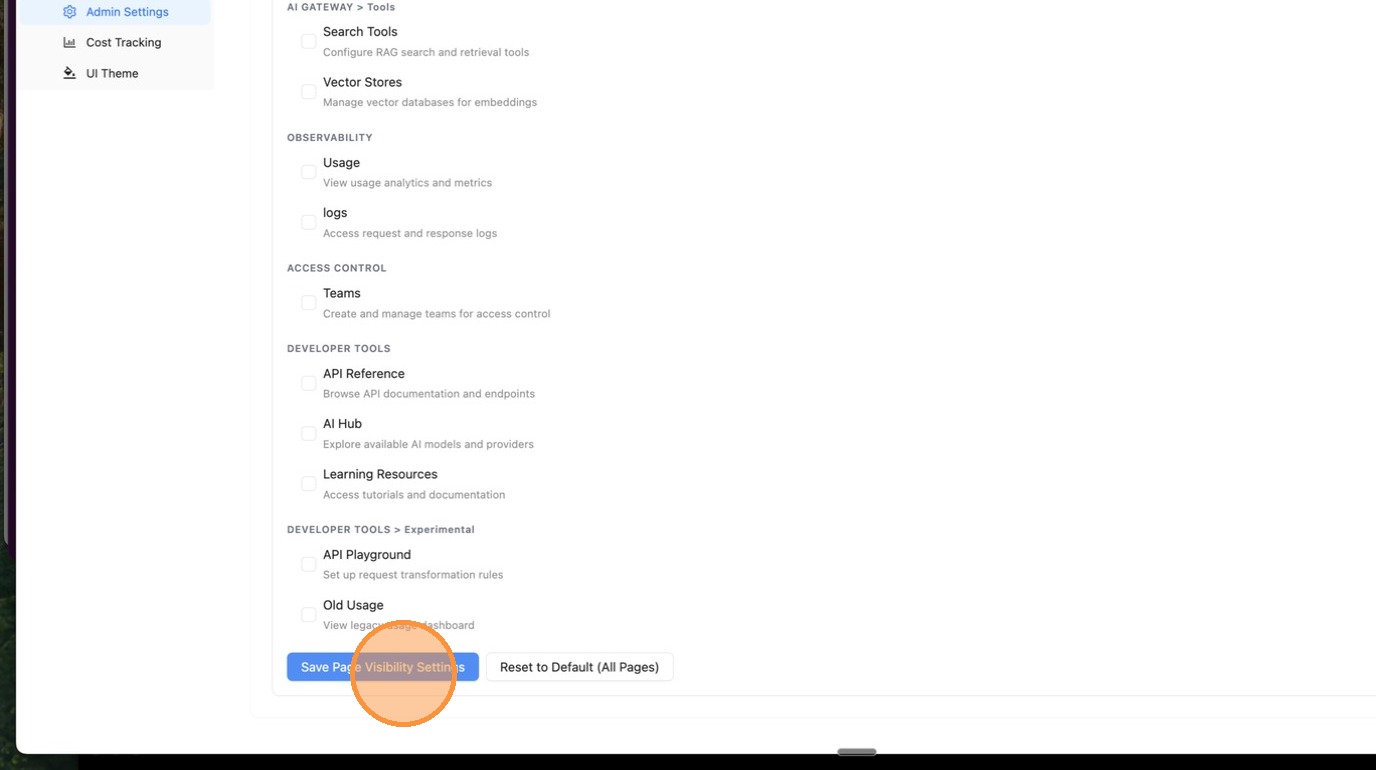
+
+### 7. Verify Changes
+
+Internal users will now only see the selected pages in their navigation sidebar.
+
+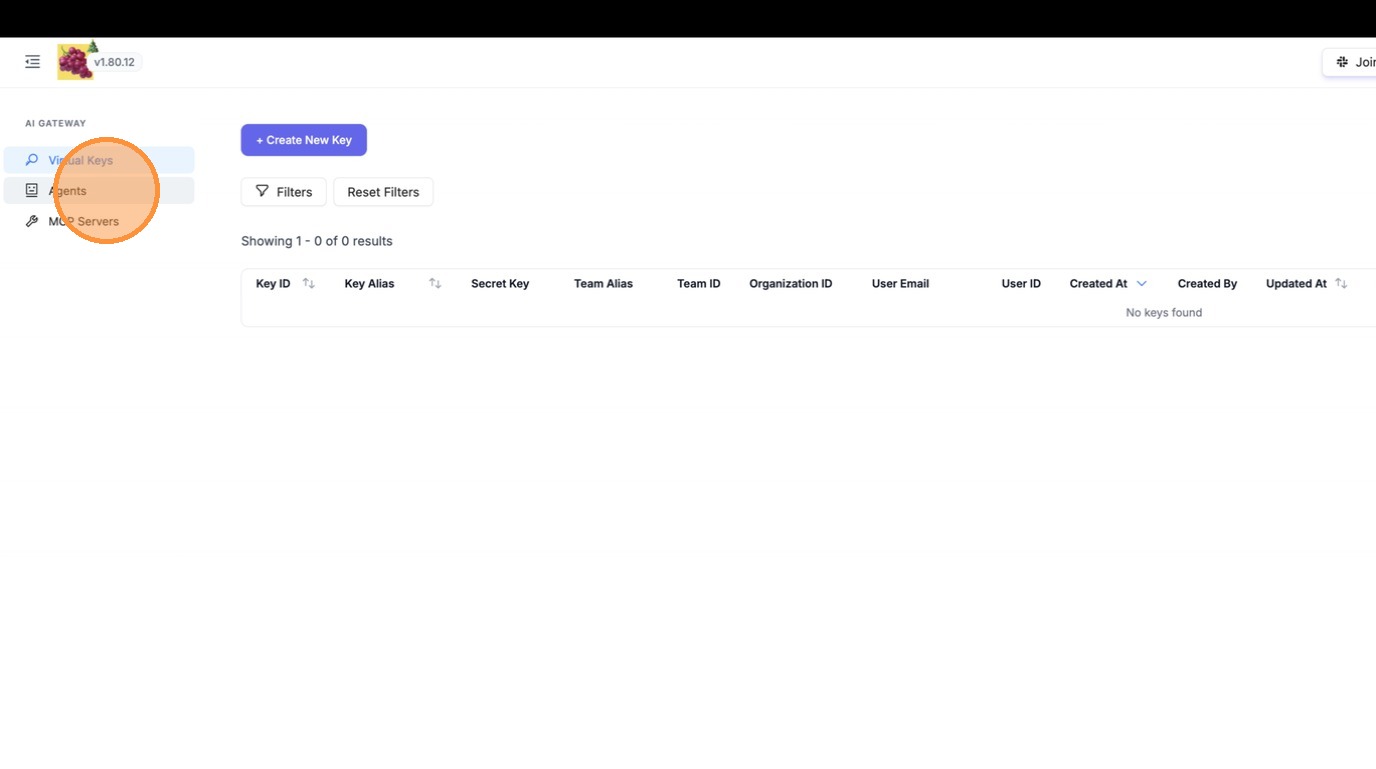
+
+## Reset to Default
+
+To restore all pages to internal users:
+
+1. Open the Page Visibility configuration
+2. Click **Reset to Default (All Pages)**
+3. Click **Save Page Visibility Settings**
+
+This will clear the restriction and show all accessible pages to internal users.
+
+## API Configuration
+
+You can also configure page visibility programmatically using the API:
+
+### Get Current Settings
+
+```bash
+curl -X GET 'http://localhost:4000/ui_settings/get' \
+ -H 'Authorization: Bearer '
+```
+
+### Update Page Visibility
+
+```bash
+curl -X PATCH 'http://localhost:4000/ui_settings/update' \
+ -H 'Authorization: Bearer ' \
+ -H 'Content-Type: application/json' \
+ -d '{
+ "enabled_ui_pages_internal_users": [
+ "api-keys",
+ "agents",
+ "mcp-servers",
+ "logs",
+ "teams"
+ ]
+ }'
+```
+
+### Clear Page Visibility Restrictions
+
+```bash
+curl -X PATCH 'http://localhost:4000/ui_settings/update' \
+ -H 'Authorization: Bearer ' \
+ -H 'Content-Type: application/json' \
+ -d '{
+ "enabled_ui_pages_internal_users": null
+ }'
+```
+
diff --git a/docs/my-website/docs/proxy/ui_logs.md b/docs/my-website/docs/proxy/ui_logs.md
index 61f328011c3..8cfe818ebfd 100644
--- a/docs/my-website/docs/proxy/ui_logs.md
+++ b/docs/my-website/docs/proxy/ui_logs.md
@@ -25,7 +25,10 @@ View Spend, Token Usage, Key, Team Name for Each Request to LiteLLM
## Tracking - Request / Response Content in Logs Page
-If you want to view request and response content on LiteLLM Logs, you need to opt in with this setting
+If you want to view request and response content on LiteLLM Logs, you can enable it in either place:
+
+- **From the UI (no restart):** Use [UI Spend Log Settings](./ui_spend_log_settings.md) — open Logs → Settings → enable "Store Prompts in Spend Logs" → Save. Takes effect immediately and overrides config.
+- **From config:** Add this to your `proxy_config.yaml` (requires restart):
```yaml
general_settings:
@@ -34,6 +37,40 @@ general_settings:
+## Tracing Tools
+
+View which tools were provided and called in your completion requests.
+
+
+
+**Example:** Make a completion request with tools:
+
+```bash
+curl -X POST 'http://localhost:4000/chat/completions' \
+ -H 'Authorization: Bearer sk-1234' \
+ -H 'Content-Type: application/json' \
+ -d '{
+ "model": "gpt-4",
+ "messages": [{"role": "user", "content": "What is the weather?"}],
+ "tools": [
+ {
+ "type": "function",
+ "function": {
+ "name": "get_weather",
+ "description": "Get the current weather",
+ "parameters": {
+ "type": "object",
+ "properties": {
+ "location": {"type": "string"}
+ }
+ }
+ }
+ }
+ ]
+ }'
+```
+
+Check the Logs page to see all tools provided and which ones were called.
## Stop storing Error Logs in DB
@@ -57,7 +94,10 @@ general_settings:
If you're storing spend logs, it might be a good idea to delete them regularly to keep the database fast.
-LiteLLM lets you configure this in your `proxy_config.yaml`:
+You can set the retention period in either place:
+
+- **From the UI (no restart):** [UI Spend Log Settings](./ui_spend_log_settings.md) — Logs → Settings → set Retention Period → Save.
+- **From config:** Add the following to your `proxy_config.yaml` (requires restart):
```yaml
general_settings:
diff --git a/docs/my-website/docs/proxy/ui_spend_log_settings.md b/docs/my-website/docs/proxy/ui_spend_log_settings.md
new file mode 100644
index 00000000000..5e04974e3a7
--- /dev/null
+++ b/docs/my-website/docs/proxy/ui_spend_log_settings.md
@@ -0,0 +1,92 @@
+import Image from '@theme/IdealImage';
+
+# UI Spend Log Settings
+
+Configure spend log behavior directly from the Admin UI—no config file edits or proxy restart required. This is especially useful for cloud deployments where updating the config is difficult or requires a long release process.
+
+## Overview
+
+Previously, spend log options (such as storing request/response content and retention period) had to be set in `proxy_config.yaml` under `general_settings`. Changing them required editing the config and restarting the proxy, which was a pain point for users-especially in cloud environments—who don't have easy access to the config or whose deployment process makes config updates slow.
+
+
+
+**UI Spend Log Settings** lets you:
+
+- **Store prompts in spend logs** – Enable or disable storing request and response content in the spend logs table (only affects logs created after you change the setting)
+- **Set retention period** – Configure how long spend logs are kept before automatic cleanup (e.g. `7d`, `30d`)
+- **Apply changes immediately** – No proxy restart needed; settings take effect for new requests as soon as you save
+
+:::warning UI overrides config
+Settings changed in the UI **override** the values in your config file. For example, if `store_prompts_in_spend_logs` is explicitly set to `false` in `general_settings`, turning it on in the UI will still enable storing prompts. Use the UI when you want runtime control without redeploying.
+:::
+
+## Settings You Can Configure
+
+| Setting | Description |
+| ------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
+| **Store Prompts in Spend Logs** | When enabled, request messages and response content are stored for **new** spend logs so you can view them in the Logs UI. Logs created before you enabled this will not have request/response content. When disabled, only metadata (e.g. tokens, cost, model) is stored for new logs. |
+| **Retention Period** | Maximum time to keep spend logs before they are automatically deleted (e.g. `7d`, `30d`). Optional; if not set, logs are retained according to your config or default behavior. |
+
+The same options can be set in config via [general_settings](./config_settings.md#general_settings---reference) (`store_prompts_in_spend_logs`, `maximum_spend_logs_retention_period`). Values set in the UI take precedence.
+
+## How to Configure Spend Log Settings in the UI
+
+### 1. Open the Logs page
+
+Navigate to the Admin UI (e.g. `http://localhost:4000/ui` or your `PROXY_BASE_URL/ui`) and click **Logs**.
+
+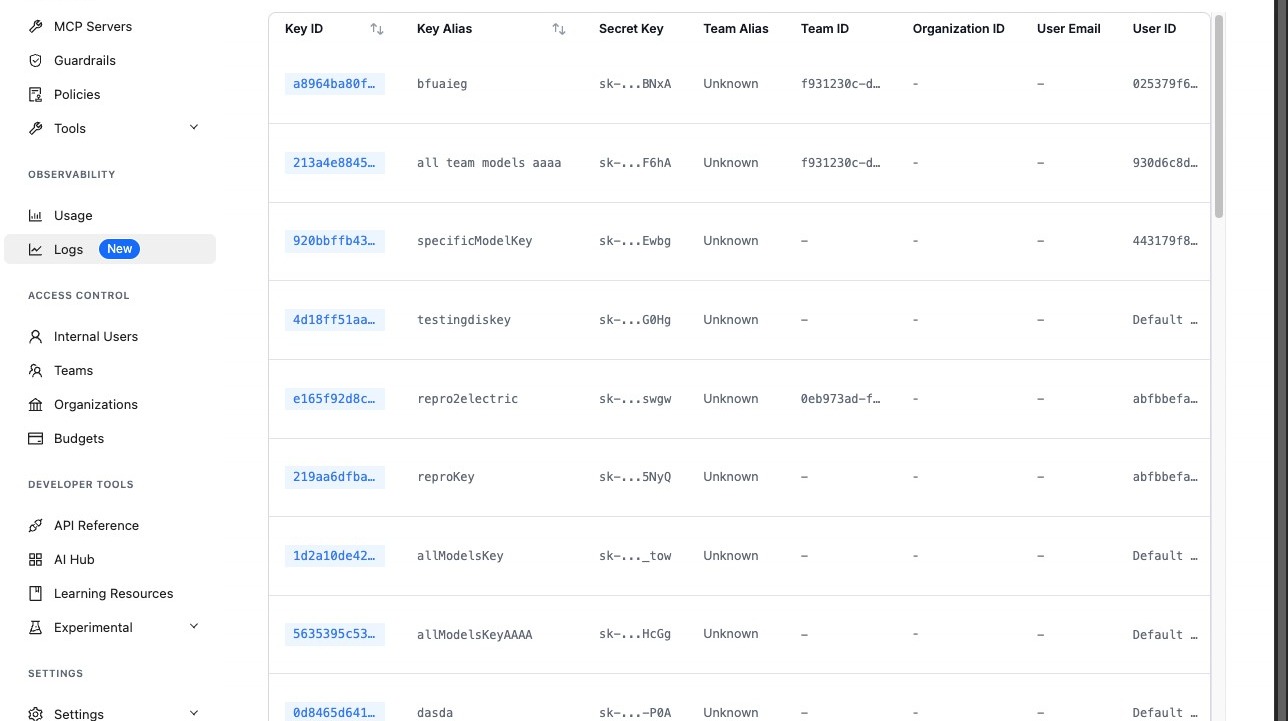
+
+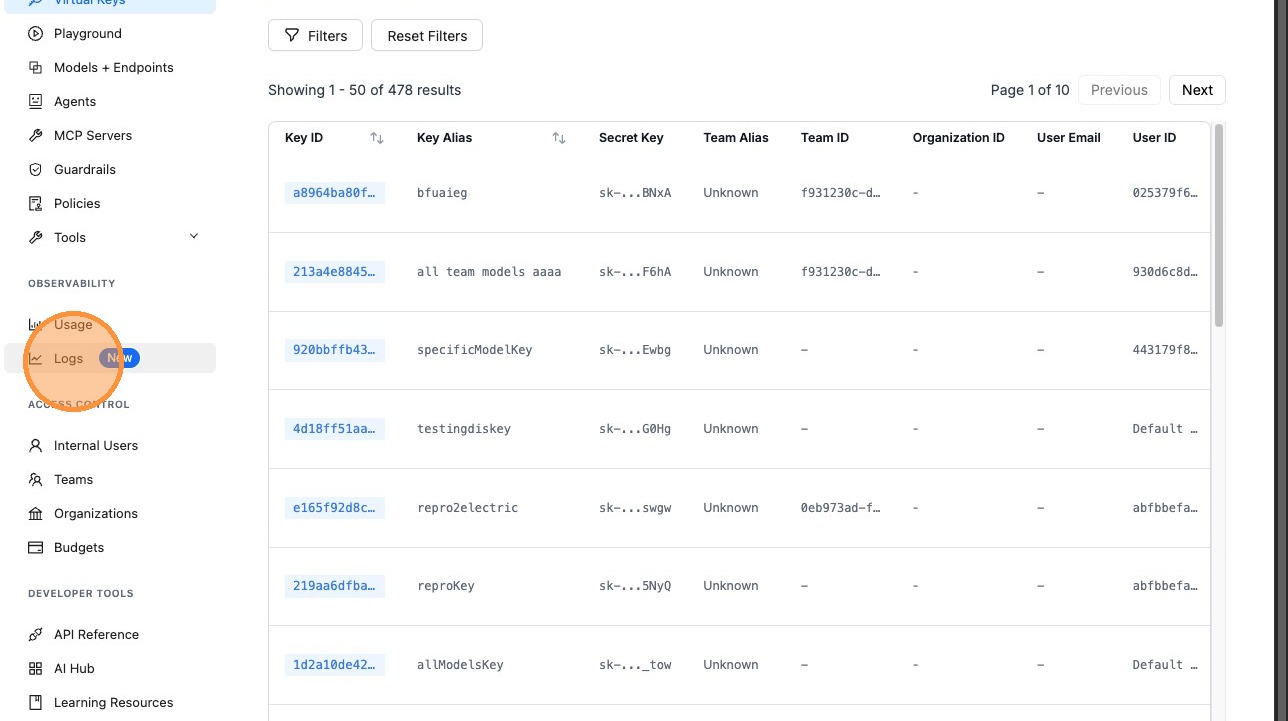
+
+### 2. Open Logs settings
+
+Click the **Settings** (gear) icon on the Logs page to open the spend log settings panel.
+
+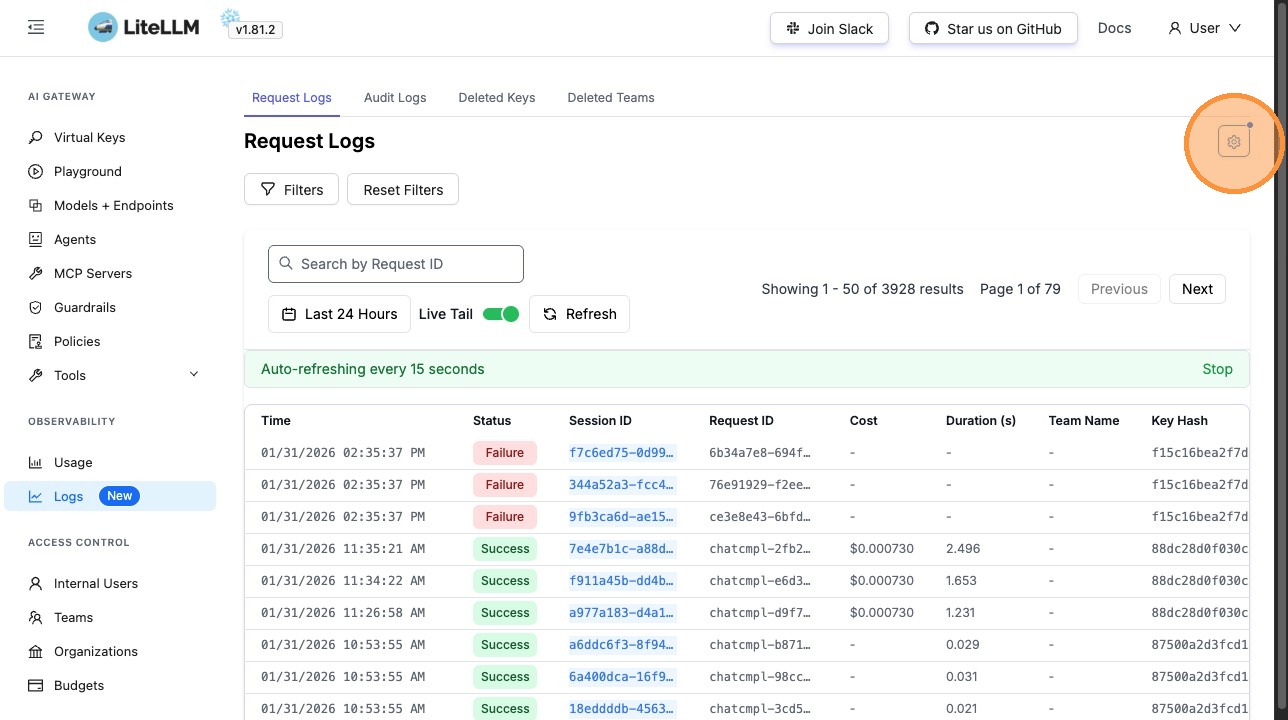
+
+### 3. Enable Store Prompts in Spend Logs (optional)
+
+Turn on **Store Prompts in Spend Logs** if you want request and response content to be stored for new requests and visible when you open those log entries. This only affects logs created after you enable it; existing logs will not gain request/response content. Leave it off if you only need metadata (tokens, cost, model, etc.).
+
+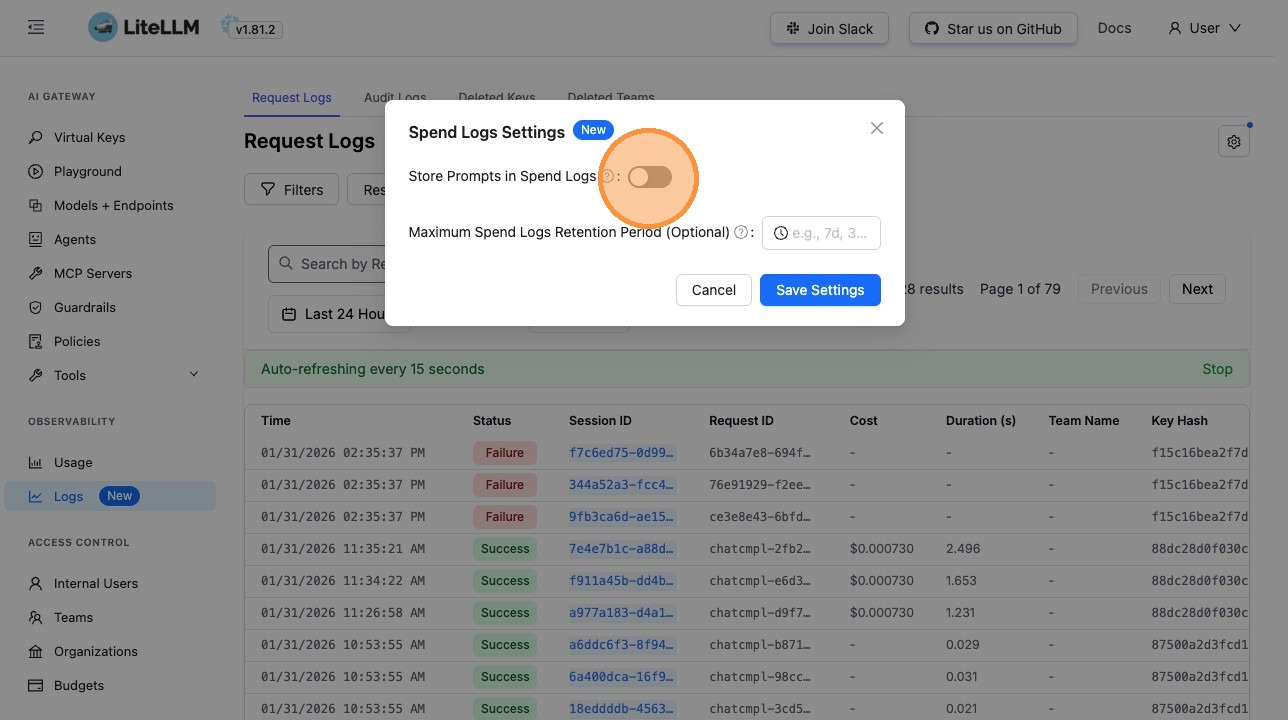
+
+### 4. Set the retention period (optional)
+
+Optionally set the **Retention Period** (e.g. `7d`, `30d`) to control how long spend logs are kept before automatic cleanup. Uses the same format as the config option `maximum_spend_logs_retention_period`.
+
+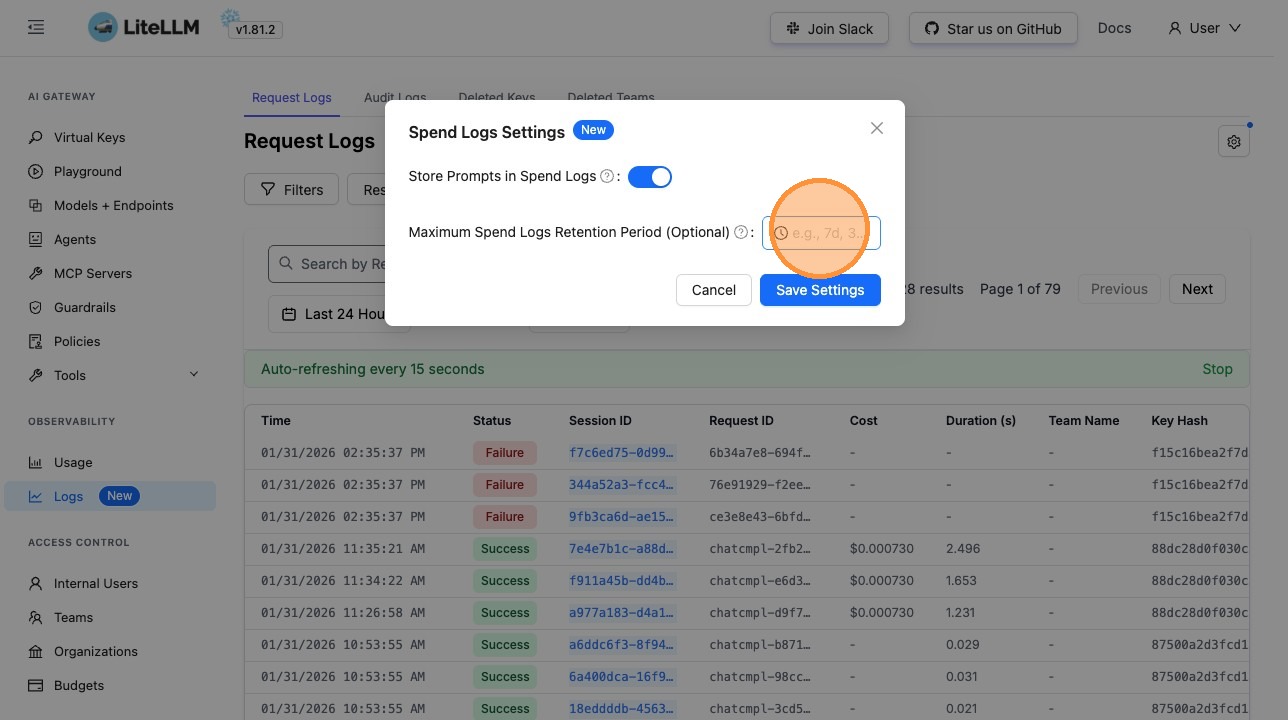
+
+### 5. Save settings
+
+Click **Save Settings**. Changes take effect immediately for new requests; no proxy restart is required. Existing logs are not updated.
+
+
+
+### 6. Verify: view request and response in a log
+
+After enabling **Store Prompts in Spend Logs**, make a new request through the proxy, then open that log entry (or any other log created after you enabled the setting). The log details view will include the request and response content. Logs that existed before you turned the setting on will not have this content.
+
+
+
+
+
+## Use Cases
+
+### Cloud and managed deployments
+
+When the proxy runs in a managed or cloud environment, config may be in a separate repo, require a long release, or be controlled by another team. Using the UI lets you change spend log behavior (e.g. enable prompt storage for debugging or set retention) without going through that process.
+
+### Quick toggles for debugging
+
+Temporarily enable **Store Prompts in Spend Logs** to inspect request/response content on new requests when debugging, then turn it off again from the UI without editing config or restarting. Only logs created while the setting was on will contain the content.
+
+### Retention without redeploying
+
+Adjust how long spend logs are retained (e.g. shorten to reduce storage or extend for compliance) and have the new retention period and cleanup job take effect immediately.
+
+## Related Documentation
+
+- [Getting Started with UI Logs](./ui_logs.md) – Overview of what gets logged and config-based options
+- [Config Settings](./config_settings.md) – `store_prompts_in_spend_logs`, `disable_spend_logs`, `maximum_spend_logs_retention_period` in `general_settings`
+- [Spend Logs Deletion](./spend_logs_deletion.md) – How retention and cleanup work
diff --git a/docs/my-website/docs/rag_ingest.md b/docs/my-website/docs/rag_ingest.md
index 1133b85f206..7adc2d70b5b 100644
--- a/docs/my-website/docs/rag_ingest.md
+++ b/docs/my-website/docs/rag_ingest.md
@@ -5,7 +5,7 @@ All-in-one document ingestion pipeline: **Upload → Chunk → Embed → Vector
| Feature | Supported |
|---------|-----------|
| Logging | Yes |
-| Supported Providers | `openai`, `bedrock`, `vertex_ai`, `gemini` |
+| Supported Providers | `openai`, `bedrock`, `vertex_ai`, `gemini`, `s3_vectors` |
:::tip
After ingesting documents, use [/rag/query](./rag_query.md) to search and generate responses with your ingested content.
@@ -75,6 +75,31 @@ curl -X POST "http://localhost:4000/v1/rag/ingest" \
}"
```
+### AWS S3 Vectors
+
+```bash showLineNumbers title="Ingest to S3 Vectors"
+curl -X POST "http://localhost:4000/v1/rag/ingest" \
+ -H "Authorization: Bearer sk-1234" \
+ -H "Content-Type: application/json" \
+ -d "{
+ \"file\": {
+ \"filename\": \"document.txt\",
+ \"content\": \"$(base64 -i document.txt)\",
+ \"content_type\": \"text/plain\"
+ },
+ \"ingest_options\": {
+ \"embedding\": {
+ \"model\": \"text-embedding-3-small\"
+ },
+ \"vector_store\": {
+ \"custom_llm_provider\": \"s3_vectors\",
+ \"vector_bucket_name\": \"my-embeddings\",
+ \"aws_region_name\": \"us-west-2\"
+ }
+ }
+ }"
+```
+
## Response
```json
@@ -265,6 +290,57 @@ When `vector_store_id` is omitted, LiteLLM automatically creates:
4. Install: `pip install 'google-cloud-aiplatform>=1.60.0'`
:::
+### vector_store (AWS S3 Vectors)
+
+| Parameter | Type | Default | Description |
+|-----------|------|---------|-------------|
+| `custom_llm_provider` | string | - | `"s3_vectors"` |
+| `vector_bucket_name` | string | **required** | S3 vector bucket name |
+| `index_name` | string | auto-create | Vector index name |
+| `dimension` | integer | auto-detect | Vector dimension (auto-detected from embedding model) |
+| `distance_metric` | string | `cosine` | Distance metric: `cosine` or `euclidean` |
+| `non_filterable_metadata_keys` | array | `["source_text"]` | Metadata keys excluded from filtering |
+| `aws_region_name` | string | `us-west-2` | AWS region |
+| `aws_access_key_id` | string | env | AWS access key |
+| `aws_secret_access_key` | string | env | AWS secret key |
+
+:::info S3 Vectors Auto-Creation
+When `index_name` is omitted, LiteLLM automatically creates:
+- S3 vector bucket (if it doesn't exist)
+- Vector index with auto-detected dimensions from your embedding model
+
+**Dimension Auto-Detection**: The vector dimension is automatically detected by making a test embedding request to your specified model. No need to manually specify dimensions!
+
+**Supported Embedding Models**: Works with any LiteLLM-supported embedding model (OpenAI, Cohere, Bedrock, Azure, etc.)
+:::
+
+**Example with auto-detection:**
+```json
+{
+ "embedding": {
+ "model": "text-embedding-3-small" // Dimension auto-detected as 1536
+ },
+ "vector_store": {
+ "custom_llm_provider": "s3_vectors",
+ "vector_bucket_name": "my-embeddings"
+ }
+}
+```
+
+**Example with custom embedding provider:**
+```json
+{
+ "embedding": {
+ "model": "cohere/embed-english-v3.0" // Dimension auto-detected as 1024
+ },
+ "vector_store": {
+ "custom_llm_provider": "s3_vectors",
+ "vector_bucket_name": "my-embeddings",
+ "distance_metric": "cosine"
+ }
+}
+```
+
## Input Examples
### File (Base64)
diff --git a/docs/my-website/docs/realtime.md b/docs/my-website/docs/realtime.md
index 0b3c823f5db..b191c82c670 100644
--- a/docs/my-website/docs/realtime.md
+++ b/docs/my-website/docs/realtime.md
@@ -3,13 +3,15 @@ import TabItem from '@theme/TabItem';
# /realtime
-Use this to loadbalance across Azure + OpenAI.
+Use this to loadbalance across Azure + OpenAI + xAI and more.
Supported Providers:
- OpenAI
- Azure
+- xAI ([see full docs](/docs/providers/xai_realtime))
- Google AI Studio (Gemini)
- Vertex AI
+- Bedrock
## Proxy Usage
@@ -45,6 +47,21 @@ model_list:
api_key: os.environ/OPENAI_API_KEY
```
+
+
+
+```yaml
+model_list:
+ - model_name: grok-voice-agent
+ litellm_params:
+ model: xai/grok-4-1-fast-non-reasoning
+ api_key: os.environ/XAI_API_KEY
+ model_info:
+ mode: realtime
+```
+
+**[See full xAI Realtime documentation →](/docs/providers/xai_realtime)**
+
diff --git a/docs/my-website/docs/routing.md b/docs/my-website/docs/routing.md
index 47967775e1e..67e7f681147 100644
--- a/docs/my-website/docs/routing.md
+++ b/docs/my-website/docs/routing.md
@@ -830,6 +830,12 @@ asyncio.run(router_acompletion())
+## Traffic Mirroring / Silent Experiments
+
+Traffic mirroring allows you to "mimic" production traffic to a secondary (silent) model for evaluation purposes. The silent model's response is gathered in the background and does not affect the latency or result of the primary request.
+
+[**See detailed guide on A/B Testing - Traffic Mirroring here**](./traffic_mirroring.md)
+
## Basic Reliability
### Deployment Ordering (Priority)
@@ -1582,11 +1588,13 @@ Get a slack webhook url from https://api.slack.com/messaging/webhooks
Initialize an `AlertingConfig` and pass it to `litellm.Router`. The following code will trigger an alert because `api_key=bad-key` which is invalid
```python
-from litellm.router import AlertingConfig
import litellm
+from litellm.router import Router
+from litellm.types.router import AlertingConfig
import os
+import asyncio
-router = litellm.Router(
+router = Router(
model_list=[
{
"model_name": "gpt-3.5-turbo",
@@ -1597,17 +1605,28 @@ router = litellm.Router(
}
],
alerting_config= AlertingConfig(
- alerting_threshold=10, # threshold for slow / hanging llm responses (in seconds). Defaults to 300 seconds
- webhook_url= os.getenv("SLACK_WEBHOOK_URL") # webhook you want to send alerts to
+ alerting_threshold=10,
+ webhook_url= "https:/..."
),
)
-try:
- await router.acompletion(
- model="gpt-3.5-turbo",
- messages=[{"role": "user", "content": "Hey, how's it going?"}],
- )
-except:
- pass
+
+async def main():
+ print(f"\n=== Configuration ===")
+ print(f"Slack logger exists: {router.slack_alerting_logger is not None}")
+
+ try:
+ await router.acompletion(
+ model="gpt-3.5-turbo",
+ messages=[{"role": "user", "content": "Hey, how's it going?"}],
+ )
+ except Exception as e:
+ print(f"\n=== Exception caught ===")
+ print(f"Waiting 10 seconds for alerts to be sent via periodic flush...")
+ await asyncio.sleep(10)
+ print(f"\n=== After waiting ===")
+ print(f"Alert should have been sent to Slack!")
+
+asyncio.run(main())
```
## Track cost for Azure Deployments
diff --git a/docs/my-website/docs/traffic_mirroring.md b/docs/my-website/docs/traffic_mirroring.md
new file mode 100644
index 00000000000..3bdcb0f1614
--- /dev/null
+++ b/docs/my-website/docs/traffic_mirroring.md
@@ -0,0 +1,83 @@
+import Tabs from '@theme/Tabs';
+import TabItem from '@theme/TabItem';
+
+# A/B Testing - Traffic Mirroring
+
+Traffic mirroring allows you to "mimic" production traffic to a secondary (silent) model for evaluation purposes. The silent model's response is gathered in the background and does not affect the latency or result of the primary request.
+
+This is useful for:
+- Testing a new model's performance on production prompts before switching.
+- Comparing costs and latency between different providers.
+- Debugging issues by mirroring traffic to a more verbose model.
+
+## Quick Start
+
+To enable traffic mirroring, add `silent_model` to the `litellm_params` of a deployment.
+
+
+
+
+```python
+from litellm import Router
+
+model_list = [
+ {
+ "model_name": "gpt-3.5-turbo",
+ "litellm_params": {
+ "model": "azure/chatgpt-v-2",
+ "api_key": "...",
+ "silent_model": "gpt-4" # 👈 Mirror traffic to gpt-4
+ },
+ },
+ {
+ "model_name": "gpt-4",
+ "litellm_params": {
+ "model": "openai/gpt-4",
+ "api_key": "..."
+ },
+ }
+]
+
+router = Router(model_list=model_list)
+
+# The request to "gpt-3.5-turbo" will trigger a background call to "gpt-4"
+response = await router.acompletion(
+ model="gpt-3.5-turbo",
+ messages=[{"role": "user", "content": "How does traffic mirroring work?"}]
+)
+```
+
+
+
+
+Add `silent_model` to your `config.yaml`:
+
+```yaml
+model_list:
+ - model_name: primary-model
+ litellm_params:
+ model: azure/gpt-35-turbo
+ api_key: os.environ/AZURE_API_KEY
+ silent_model: evaluation-model # 👈 Mirror traffic here
+ - model_name: evaluation-model
+ litellm_params:
+ model: openai/gpt-4o
+ api_key: os.environ/OPENAI_API_KEY
+```
+
+
+
+
+## How it works
+1. **Request Received**: A request is made to a model group (e.g. `primary-model`).
+2. **Deployment Picked**: LiteLLM picks a deployment from the group.
+3. **Primary Call**: LiteLLM makes the call to the primary deployment.
+4. **Mirroring**: If `silent_model` is present, LiteLLM triggers a background call to that model.
+ - For **Sync** calls: Uses a shared thread pool.
+ - For **Async** calls: Uses `asyncio.create_task`.
+5. **Isolation**: The background call uses a `deepcopy` of the original request parameters and sets `metadata["is_silent_experiment"] = True`. It also strips out logging IDs to prevent collisions in usage tracking.
+
+## Key Features
+- **Latency Isolation**: The primary request returns as soon as it's ready. The background (silent) call does not block.
+- **Unified Logging**: Background calls are processed via the Router, meaning they are automatically logged to your configured observability tools (Langfuse, S3, etc.).
+- **Evaluation**: Use the `is_silent_experiment: True` flag in your logs to filter and compare results between the primary and mirrored calls.
diff --git a/docs/my-website/docs/troubleshoot/prisma_migrations.md b/docs/my-website/docs/troubleshoot/prisma_migrations.md
new file mode 100644
index 00000000000..9d9cb585b2b
--- /dev/null
+++ b/docs/my-website/docs/troubleshoot/prisma_migrations.md
@@ -0,0 +1,113 @@
+# Troubleshooting Prisma Migration Errors
+
+Common Prisma migration issues encountered when upgrading or downgrading LiteLLM proxy versions, and how to fix them.
+
+## How Prisma Migrations Work in LiteLLM
+
+- LiteLLM uses [Prisma](https://www.prisma.io/) to manage its PostgreSQL database schema.
+- Migration history is tracked in the `_prisma_migrations` table in your database.
+- When LiteLLM starts, it runs `prisma migrate deploy` to apply any new migrations.
+- Upgrading LiteLLM applies all migrations added since your last applied version.
+
+## Common Errors
+
+### 1. `relation "X" does not exist`
+
+**Example error:**
+
+```
+ERROR: relation "LiteLLM_DeletedTeamTable" does not exist
+Migration: 20260116142756_update_deleted_keys_teams_table_routing_settings
+```
+
+**Cause:** This typically happens after a version rollback. The `_prisma_migrations` table still records migrations from the newer version as "applied," but the underlying database tables were modified, dropped, or never fully created.
+
+**How to fix:**
+
+#### Step 1 — Delete the failed migration entry and restart
+
+Remove the problematic migration from the history so it can be re-applied:
+
+```sql
+-- View recent migrations
+SELECT migration_name, finished_at, rolled_back_at, logs
+FROM "_prisma_migrations"
+ORDER BY started_at DESC
+LIMIT 10;
+
+-- Delete the failed migration entry
+DELETE FROM "_prisma_migrations"
+WHERE migration_name = '';
+```
+
+After deleting the entry, restart LiteLLM — it will re-apply the migration on startup.
+
+#### Step 2 — If that doesn't work, use `prisma db push`
+
+If deleting the migration entry and restarting doesn't resolve the issue, sync the schema directly:
+
+```bash
+DATABASE_URL="" prisma db push
+```
+
+This bypasses migration history and forces the database schema to match the Prisma schema.
+
+---
+
+### 2. `New migrations cannot be applied before the error is recovered from`
+
+**Cause:** A previous migration failed (recorded with an error in `_prisma_migrations`), and Prisma refuses to apply any new migrations until the failure is resolved.
+
+**How to fix:**
+
+1. Find the failed migration:
+
+```sql
+SELECT migration_name, finished_at, rolled_back_at, logs
+FROM "_prisma_migrations"
+WHERE finished_at IS NULL OR rolled_back_at IS NOT NULL
+ORDER BY started_at DESC;
+```
+
+2. Delete the failed entry and restart LiteLLM:
+
+```sql
+DELETE FROM "_prisma_migrations"
+WHERE migration_name = '';
+```
+
+3. If that doesn't work, use `prisma db push`:
+
+```bash
+DATABASE_URL="" prisma db push
+```
+
+---
+
+### 3. Migration state mismatch after version rollback
+
+**Cause:** You upgraded to version X (new migrations applied), rolled back to version Y, then upgraded again. The `_prisma_migrations` table has stale entries for migrations that were partially applied or correspond to a schema state that no longer exists.
+
+**Fix:**
+
+1. Inspect the migration table for problematic entries:
+
+```sql
+SELECT migration_name, started_at, finished_at, rolled_back_at, logs
+FROM "_prisma_migrations"
+ORDER BY started_at DESC
+LIMIT 20;
+```
+
+2. For each migration that shouldn't be there (i.e., from the version you rolled back from), delete the entry:
+ ```sql
+ DELETE FROM "_prisma_migrations" WHERE migration_name = '';
+ ```
+
+3. Restart LiteLLM to re-run migrations.
+
+4. If that doesn't work, use `prisma db push`:
+
+```bash
+DATABASE_URL="" prisma db push
+```
diff --git a/docs/my-website/docs/troubleshoot/spend_queue_warnings.md b/docs/my-website/docs/troubleshoot/spend_queue_warnings.md
new file mode 100644
index 00000000000..4be8b18f5cd
--- /dev/null
+++ b/docs/my-website/docs/troubleshoot/spend_queue_warnings.md
@@ -0,0 +1,46 @@
+# Spend Update Queue Full Warnings
+
+## Overview
+
+The "Spend update queue is full" warning occurs in high-volume LiteLLM proxy deployments when the internal spend tracking queue reaches capacity. This is a protective mechanism to prevent memory issues during traffic spikes.
+
+## Warning Message
+
+```
+WARNING:litellm.proxy.db.db_transaction_queue.spend_update_queue:Spend update queue is full. Aggregating entries to prevent memory issues.
+```
+
+## Root Cause
+
+The spend update queue has a default maximum size of 10,000 entries (`MAX_SIZE_IN_MEMORY_QUEUE=10000`). When this limit is reached:
+
+1. New spend tracking entries are aggregated instead of queued individually
+2. This prevents memory exhaustion but may slightly delay spend updates
+3. The warning indicates your deployment is processing requests faster than the database can handle spend updates
+
+## Solutions
+
+### 1. Increase Queue Size
+
+Set the `MAX_SIZE_IN_MEMORY_QUEUE` environment variable to a higher value:
+
+```bash
+MAX_SIZE_IN_MEMORY_QUEUE=50000
+```
+
+**Tradeoffs:**
+Higher queue sizes store more items in memory - provision at least 8GB RAM for large queues
+- Recommended for deployments with consistent high traffic
+
+### 2. Horizontal Scaling
+
+Deploy multiple proxy instances with load balancing. This distributes the spend tracking load across multiple queues, reducing the pressure on any single instance's spend update queue.
+
+
+
+## Related Configuration
+
+```yaml
+# Environment variables
+MAX_SIZE_IN_MEMORY_QUEUE: 10000 # Default queue size
+```
diff --git a/docs/my-website/docs/tutorials/claude_agent_sdk.md b/docs/my-website/docs/tutorials/claude_agent_sdk.md
new file mode 100644
index 00000000000..c56784ba2df
--- /dev/null
+++ b/docs/my-website/docs/tutorials/claude_agent_sdk.md
@@ -0,0 +1,115 @@
+import Tabs from '@theme/Tabs';
+import TabItem from '@theme/TabItem';
+
+# Claude Agent SDK with LiteLLM
+
+Use Anthropic's Claude Agent SDK with any LLM provider through LiteLLM Proxy.
+
+The Claude Agent SDK provides a high-level interface for building AI agents. By pointing it to LiteLLM, you can use the same agent code with OpenAI, Bedrock, Azure, Vertex AI, or any other provider.
+
+## Quick Start
+
+### 1. Install Dependencies
+
+```bash
+pip install claude-agent-sdk
+```
+
+### 2. Start LiteLLM Proxy
+
+```yaml title="config.yaml" showLineNumbers
+model_list:
+ - model_name: bedrock-claude-sonnet-3.5
+ litellm_params:
+ model: "bedrock/us.anthropic.claude-3-5-sonnet-20240620-v1:0"
+ aws_region_name: "us-east-1"
+
+ - model_name: bedrock-claude-sonnet-4
+ litellm_params:
+ model: "bedrock/us.anthropic.claude-sonnet-4-20250514-v1:0"
+ aws_region_name: "us-east-1"
+
+ - model_name: bedrock-claude-sonnet-4.5
+ litellm_params:
+ model: "bedrock/us.anthropic.claude-sonnet-4-5-20250929-v1:0"
+ aws_region_name: "us-east-1"
+
+ - model_name: bedrock-claude-opus-4.5
+ litellm_params:
+ model: "bedrock/us.anthropic.claude-opus-4-5-20251101-v1:0"
+ aws_region_name: "us-east-1"
+
+ - model_name: bedrock-nova-premier
+ litellm_params:
+ model: "bedrock/amazon.nova-premier-v1:0"
+ aws_region_name: "us-east-1"
+```
+
+```bash
+litellm --config config.yaml
+```
+
+### 3. Point Agent SDK to LiteLLM
+
+| Environment Variable | Value | Description |
+|---------------------|-------|-------------|
+| `ANTHROPIC_BASE_URL` | `http://localhost:4000` | LiteLLM proxy URL |
+| `ANTHROPIC_API_KEY` | `sk-1234` | Your LiteLLM API key (not Anthropic key) |
+
+```python title="agent.py" showLineNumbers
+import os
+from claude_agent_sdk import ClaudeSDKClient, ClaudeAgentOptions
+
+# Point to LiteLLM proxy (not Anthropic)
+os.environ["ANTHROPIC_BASE_URL"] = "http://localhost:4000"
+os.environ["ANTHROPIC_API_KEY"] = "sk-1234" # Your LiteLLM key
+
+# Configure agent with any model from your config
+options = ClaudeAgentOptions(
+ system_prompt="You are a helpful AI assistant.",
+ model="bedrock-claude-sonnet-4", # Use any model from config.yaml
+ max_turns=20,
+)
+
+async with ClaudeSDKClient(options=options) as client:
+ await client.query("What is LiteLLM?")
+
+ async for msg in client.receive_response():
+ if hasattr(msg, 'content'):
+ for content_block in msg.content:
+ if hasattr(content_block, 'text'):
+ print(content_block.text, end='', flush=True)
+```
+
+
+
+## Why Use LiteLLM with Agent SDK?
+
+| Feature | Benefit |
+|---------|---------|
+| **Multi-Provider** | Use the same agent code with OpenAI, Bedrock, Azure, Vertex AI, etc. |
+| **Cost Tracking** | Track spending across all agent conversations |
+| **Rate Limiting** | Set budgets and limits on agent usage |
+| **Load Balancing** | Distribute requests across multiple API keys or regions |
+| **Fallbacks** | Automatically retry with different models if one fails |
+
+## Complete Example
+
+See our [cookbook example](https://github.com/BerriAI/litellm/tree/main/cookbook/anthropic_agent_sdk) for a complete interactive CLI agent that:
+- Streams responses in real-time
+- Switches between models dynamically
+- Fetches available models from the proxy
+
+```bash
+# Clone and run the example
+git clone https://github.com/BerriAI/litellm.git
+cd litellm/cookbook/anthropic_agent_sdk
+pip install -r requirements.txt
+python main.py
+```
+
+## Related Resources
+
+- [Claude Agent SDK Documentation](https://github.com/anthropics/anthropic-agent-sdk)
+- [LiteLLM Proxy Quick Start](../proxy/quick_start)
+- [Complete Cookbook Example](https://github.com/BerriAI/litellm/tree/main/cookbook/anthropic_agent_sdk)
diff --git a/docs/my-website/docs/tutorials/claude_code_beta_headers.md b/docs/my-website/docs/tutorials/claude_code_beta_headers.md
new file mode 100644
index 00000000000..9c1645e0277
--- /dev/null
+++ b/docs/my-website/docs/tutorials/claude_code_beta_headers.md
@@ -0,0 +1,129 @@
+import Image from '@theme/IdealImage';
+
+# Claude Code - Fixing Invalid Beta Header Errors
+
+When using Claude Code with LiteLLM and non-Anthropic providers (Bedrock, Azure AI, Vertex AI), you may encounter "invalid beta header" errors. This guide explains how to fix these errors locally or contribute a fix to LiteLLM.
+
+## What Are Beta Headers?
+
+Anthropic uses beta headers to enable experimental features in Claude. When you use Claude Code, it may send beta headers like:
+
+```
+anthropic-beta: prompt-caching-scope-2026-01-05,advanced-tool-use-2025-11-20
+```
+
+However, not all providers support all Anthropic beta features. When an unsupported beta header is sent to a provider, you'll see an error.
+
+## Common Error Message
+
+```bash
+Error: The model returned the following errors: invalid beta flag
+```
+
+## How LiteLLM Handles Beta Headers
+
+LiteLLM automatically filters out unsupported beta headers using a configuration file:
+
+```
+litellm/litellm/anthropic_beta_headers_config.json
+```
+
+This JSON file lists which beta headers are **unsupported** for each provider. Headers not in the unsupported list are passed through to the provider.
+
+## Quick Fix: Update Config Locally
+
+If you encounter an invalid beta header error, you can fix it immediately by updating the config file locally.
+
+### Step 1: Locate the Config File
+
+Find the file in your LiteLLM installation:
+
+```bash
+# If installed via pip
+cd $(python -c "import litellm; import os; print(os.path.dirname(litellm.__file__))")
+
+# The config file is at:
+# litellm/anthropic_beta_headers_config.json
+```
+
+### Step 2: Add the Unsupported Header
+
+Open `anthropic_beta_headers_config.json` and add the problematic header to the appropriate provider's list:
+
+```json title="anthropic_beta_headers_config.json"
+{
+ "description": "Unsupported Anthropic beta headers for each provider. Headers listed here will be dropped. Headers not listed are passed through as-is.",
+ "anthropic": [],
+ "azure_ai": [],
+ "bedrock_converse": [
+ "prompt-caching-scope-2026-01-05",
+ "bash_20250124",
+ "bash_20241022",
+ "text_editor_20250124",
+ "text_editor_20241022",
+ "compact-2026-01-12",
+ "advanced-tool-use-2025-11-20",
+ "web-fetch-2025-09-10",
+ "code-execution-2025-08-25",
+ "skills-2025-10-02",
+ "files-api-2025-04-14"
+ ],
+ "bedrock": [
+ "advanced-tool-use-2025-11-20",
+ "prompt-caching-scope-2026-01-05",
+ "structured-outputs-2025-11-13",
+ "web-fetch-2025-09-10",
+ "code-execution-2025-08-25",
+ "skills-2025-10-02",
+ "files-api-2025-04-14"
+ ],
+ "vertex_ai": [
+ "prompt-caching-scope-2026-01-05"
+ ]
+}
+```
+
+### Step 3: Restart Your Application
+
+After updating the config file, restart your LiteLLM proxy or application:
+
+```bash
+# If using LiteLLM proxy
+litellm --config config.yaml
+
+# If using Python SDK
+# Just restart your Python application
+```
+
+The updated configuration will be loaded automatically.
+
+## Contributing a Fix to LiteLLM
+
+Help the community by contributing your fix! If your local changes work, please raise a PR with the addition of the header and we will merge it.
+
+
+## How Beta Header Filtering Works
+
+When you make a request through LiteLLM:
+
+```mermaid
+sequenceDiagram
+ participant CC as Claude Code
+ participant LP as LiteLLM
+ participant Config as Beta Headers Config
+ participant Provider as Provider (Bedrock/Azure/etc)
+
+ CC->>LP: Request with beta headers
+ Note over CC,LP: anthropic-beta: header1,header2,header3
+
+ LP->>Config: Load unsupported headers for provider
+ Config-->>LP: Returns unsupported list
+
+ Note over LP: Filter headers: - Remove unsupported - Keep supported
+
+ LP->>Provider: Request with filtered headers
+ Note over LP,Provider: anthropic-beta: header2 (header1, header3 removed)
+
+ Provider-->>LP: Success response
+ LP-->>CC: Response
+```
\ No newline at end of file
diff --git a/docs/my-website/docs/tutorials/claude_code_plugin_marketplace.md b/docs/my-website/docs/tutorials/claude_code_plugin_marketplace.md
index 946fb47d92a..9d93c717c4f 100644
--- a/docs/my-website/docs/tutorials/claude_code_plugin_marketplace.md
+++ b/docs/my-website/docs/tutorials/claude_code_plugin_marketplace.md
@@ -2,7 +2,7 @@ import Image from '@theme/IdealImage';
import Tabs from '@theme/Tabs';
import TabItem from '@theme/TabItem';
-# Claude Code Plugin Marketplace
+# Claude Code Plugin Marketplace (Managed Skills)
LiteLLM AI Gateway acts as a central registry for Claude Code plugins. Admins can govern which plugins are available across the organization, and engineers can discover and install approved plugins from a single source.
@@ -252,7 +252,7 @@ curl -X POST http://localhost:4000/claude-code/plugins \
}'
```
-### 3. Share with Your Team
+### 3. Use in Claude Code
Send engineers the marketplace URL:
diff --git a/docs/my-website/docs/tutorials/copilotkit_sdk.md b/docs/my-website/docs/tutorials/copilotkit_sdk.md
new file mode 100644
index 00000000000..fc4db8bfe3e
--- /dev/null
+++ b/docs/my-website/docs/tutorials/copilotkit_sdk.md
@@ -0,0 +1,99 @@
+import Tabs from '@theme/Tabs';
+import TabItem from '@theme/TabItem';
+
+# CopilotKit SDK with LiteLLM
+
+Use CopilotKit SDK with any LLM provider through LiteLLM Proxy.
+
+> **Note:** CopilotKit SDK integration with LiteLLM Proxy works with LiteLLM v1.81.7-nightly or higher.
+
+
+## Quick Start
+
+### 1. Add Model to Config
+
+```yaml title="config.yaml"
+model_list:
+ - model_name: claude-sonnet-4-5
+ litellm_params:
+ model: "anthropic/claude-sonnet-4-5-20250514-v1:0"
+ api_key: "os.environ/ANTHROPIC_API_KEY"
+```
+
+### 2. Start LiteLLM Proxy
+
+```bash
+litellm --config config.yaml
+```
+
+### 3. Use CopilotKit SDK
+
+```typescript
+import OpenAI from "openai";
+import {
+ CopilotRuntime,
+ OpenAIAdapter,
+ copilotRuntimeNextJSAppRouterEndpoint,
+} from "@copilotkit/runtime";
+import { NextRequest } from "next/server";
+
+const model = "claude-sonnet-4-5";
+
+const openai = new OpenAI({
+ apiKey: process.env.OPENAI_API_KEY || "sk-12345",
+ baseURL: process.env.OPENAI_BASE_URL || "http://localhost:4000/v1",
+});
+
+const serviceAdapter = new OpenAIAdapter({ openai, model });
+const runtime = new CopilotRuntime();
+
+export const POST = async (req: NextRequest) => {
+ const { handleRequest } = copilotRuntimeNextJSAppRouterEndpoint({
+ runtime,
+ serviceAdapter,
+ endpoint: "/api/copilotkit",
+ });
+ return handleRequest(req);
+};
+```
+
+### 4. Test
+
+```bash
+curl -X POST http://localhost:3000/api/copilotkit \
+ -H "Content-Type: application/json" \
+ -d '{
+ "method": "agent/run",
+ "params": {
+ "agentId": "default"
+ },
+ "runId": "your_run_id",
+ "threadId": "your_thread_id",
+ "runId": ""your_run_id"",
+ "tools": [],
+ "context": [],
+ "forwardedProps": {},
+ "state": {},
+ "messages": [
+ {
+ "id": "166e573e-f7c6-4c0f-8685-04dbefec18be",
+ "content": "Hi",
+ "role": "user"
+ }
+ ]
+ }
+}'
+```
+
+## Environment Variables
+
+| Variable | Value | Description |
+|----------|-------|-------------|
+| `OPENAI_API_KEY` | `sk-12345` | Your LiteLLM API key |
+| `OPENAI_BASE_URL` | `http://localhost:4000/v1` | LiteLLM proxy URL |
+
+
+## Related Resources
+
+- [CopilotKit Documentation](https://docs.copilotkit.ai)
+- [LiteLLM Proxy Quick Start](../proxy/quick_start)
diff --git a/docs/my-website/docs/tutorials/livekit_xai_realtime.md b/docs/my-website/docs/tutorials/livekit_xai_realtime.md
new file mode 100644
index 00000000000..1d70186382f
--- /dev/null
+++ b/docs/my-website/docs/tutorials/livekit_xai_realtime.md
@@ -0,0 +1,190 @@
+import Tabs from '@theme/Tabs';
+import TabItem from '@theme/TabItem';
+
+# LiveKit xAI Realtime Voice Agent
+
+Use LiveKit's xAI Grok Voice Agent plugin with LiteLLM Proxy to build low-latency voice AI agents.
+
+The LiveKit Agents framework provides tools for building real-time voice and video AI applications. By routing through LiteLLM Proxy, you get unified access to multiple realtime voice providers, cost tracking, rate limiting, and more.
+
+## Quick Start
+
+### 1. Install Dependencies
+
+```bash
+pip install livekit-agents[xai]
+```
+
+### 2. Start LiteLLM Proxy
+
+Create a config file with your xAI realtime model:
+
+```yaml title="config.yaml" showLineNumbers
+model_list:
+ - model_name: grok-voice-agent
+ litellm_params:
+ model: xai/grok-2-vision-1212
+ api_key: os.environ/XAI_API_KEY
+ model_info:
+ mode: realtime
+
+litellm_settings:
+ drop_params: True
+
+general_settings:
+ master_key: sk-1234 # Change this to a secure key
+```
+
+Start the proxy:
+
+```bash
+litellm --config config.yaml --port 4000
+```
+
+### 3. Configure LiveKit xAI Plugin
+
+Point LiveKit's xAI plugin to your LiteLLM proxy:
+
+```python
+from livekit.plugins import xai
+
+# Configure xAI to use LiteLLM proxy
+model = xai.realtime.RealtimeModel(
+ voice="ara", # Voice option
+ api_key="sk-1234", # Your LiteLLM proxy master key
+ base_url="http://localhost:4000", # LiteLLM proxy URL
+)
+```
+
+## Complete Example
+
+Here's a complete working example:
+
+
+
+
+```python
+#!/usr/bin/env python3
+"""
+Simple xAI realtime voice agent through LiteLLM proxy.
+"""
+import asyncio
+import json
+import websockets
+
+PROXY_URL = "ws://localhost:4000/v1/realtime"
+API_KEY = "sk-1234"
+MODEL = "grok-voice-agent"
+
+async def run_voice_agent():
+ """Connect to xAI realtime API through LiteLLM proxy"""
+ url = f"{PROXY_URL}?model={MODEL}"
+ headers = {"Authorization": f"Bearer {API_KEY}"}
+
+ async with websockets.connect(url, extra_headers=headers) as ws:
+ # Wait for initial connection event
+ initial = json.loads(await ws.recv())
+ print(f"✅ Connected: {initial['type']}")
+
+ # Send user message
+ await ws.send(json.dumps({
+ "type": "conversation.item.create",
+ "item": {
+ "type": "message",
+ "role": "user",
+ "content": [{
+ "type": "input_text",
+ "text": "Hello! Tell me a joke."
+ }]
+ }
+ }))
+
+ # Request response
+ await ws.send(json.dumps({
+ "type": "response.create",
+ "response": {"modalities": ["text", "audio"]}
+ }))
+
+ # Collect response
+ transcript = []
+ async for message in ws:
+ event = json.loads(message)
+
+ # Capture text response
+ if event['type'] == 'response.output_audio_transcript.delta':
+ transcript.append(event['delta'])
+ print(event['delta'], end='', flush=True)
+
+ # Done when response completes
+ elif event['type'] == 'response.done':
+ break
+
+ print(f"\n\n✅ Full response: {''.join(transcript)}")
+
+if __name__ == "__main__":
+ asyncio.run(run_voice_agent())
+```
+
+
+
+
+
+```python
+from livekit.agents import Agent, AgentSession, WorkerOptions, cli
+from livekit.plugins import xai
+
+class VoiceAgent(Agent):
+ def __init__(self):
+ super().__init__(
+ instructions="You are a helpful voice assistant.",
+ llm=xai.realtime.RealtimeModel(
+ voice="ara",
+ api_key="sk-1234",
+ base_url="http://localhost:4000",
+ ),
+ )
+
+if __name__ == "__main__":
+ cli.run_app(
+ WorkerOptions(
+ agent_factory=VoiceAgent,
+ )
+ )
+```
+
+
+
+
+## Running the Example
+
+1. **Start LiteLLM Proxy** (if not already running):
+ ```bash
+ litellm --config config.yaml --port 4000
+ ```
+
+2. **Run the example**:
+ ```bash
+ python your_script.py
+ ```
+
+## Expected Output
+
+```
+✅ Connected: conversation.created
+Hello! Here's a joke for you: Why don't scientists trust atoms?
+Because they make up everything!
+
+✅ Full response: Hello! Here's a joke for you: Why don't scientists trust atoms? Because they make up everything!
+```
+
+
+## Complete Working Example
+
+**[LiveKit Agent SDK Cookbook](https://github.com/BerriAI/litellm/tree/main/cookbook/livekit_agent_sdk)**
+
+
+## Learn More
+
+- [xAI Realtime API](/docs/providers/xai_realtime)
+- [LiveKit xAI Plugin](https://docs.livekit.io/agents/models/realtime/plugins/xai/)
+- [LiteLLM Realtime API](/docs/realtime)
diff --git a/docs/my-website/docs/tutorials/opencode_integration.md b/docs/my-website/docs/tutorials/opencode_integration.md
new file mode 100644
index 00000000000..e55367833f2
--- /dev/null
+++ b/docs/my-website/docs/tutorials/opencode_integration.md
@@ -0,0 +1,301 @@
+import Image from '@theme/IdealImage';
+import Tabs from '@theme/Tabs';
+import TabItem from '@theme/TabItem';
+
+# OpenCode Quickstart
+
+This tutorial shows how to connect OpenCode to your existing LiteLLM instance and switch between models.
+
+:::info
+
+This integration allows you to use any LiteLLM supported model through OpenCode with centralized authentication, usage tracking, and cost controls.
+
+:::
+
+
+
+### Video Walkthrough
+
+
+
+## Prerequisites
+
+- LiteLLM already configured and running (e.g., http://localhost:4000)
+- LiteLLM API key
+
+## Installation
+
+### Step 1: Install OpenCode
+
+Choose your preferred installation method:
+
+
+
+
+```bash
+curl -fsSL https://opencode.ai/install | bash
+```
+
+
+
+
+```bash
+npm install -g opencode-ai
+```
+
+
+
+
+```bash
+brew install sst/tap/opencode
+```
+
+
+
+
+Verify installation:
+
+```bash
+opencode --version
+```
+
+### Step 2: Configure LiteLLM Provider
+
+Create your OpenCode configuration file. You can place this in different locations depending on your needs:
+
+**Configuration locations:**
+- **Global**: `~/.config/opencode/opencode.json` (applies to all projects)
+- **Project**: `opencode.json` in your project root (project-specific settings)
+- **Custom**: Set `OPENCODE_CONFIG` environment variable
+
+Create `~/.config/opencode/opencode.json` (global config):
+
+```json
+{
+ "$schema": "https://opencode.ai/config.json",
+ "provider": {
+ "litellm": {
+ "npm": "@ai-sdk/openai-compatible",
+ "name": "LiteLLM",
+ "options": {
+ "baseURL": "http://localhost:4000/v1"
+ },
+ "models": {
+ "gpt-4": {
+ "name": "GPT-4"
+ },
+ "claude-3-5-sonnet-20241022": {
+ "name": "Claude 3.5 Sonnet"
+ },
+ "deepseek-chat": {
+ "name": "DeepSeek Chat"
+ }
+ }
+ }
+ }
+}
+```
+
+:::tip
+The keys in the "models" object (e.g., "gpt-4", "claude-3-5-sonnet-20241022") should match the `model_name` values from your LiteLLM configuration. The "name" field provides a friendly display name that will appear as an alias in OpenCode.
+:::
+
+### Step 3: Connect to LiteLLM Provider
+
+Launch OpenCode:
+
+```bash
+opencode
+```
+
+Add your API key:
+
+```bash
+/connect
+```
+
+Then:
+- **Enter provider name**: `LiteLLM` (must match the "name" field in your config)
+- **Enter your LiteLLM API key**: Your LiteLLM master key or virtual key
+
+### Step 4: Switch Between Models
+
+In OpenCode, run:
+
+```bash
+/models
+```
+
+Select any model from your LiteLLM configuration. OpenCode will route all requests through your LiteLLM instance.
+
+## Advanced Configuration
+
+### Model Parameters
+
+You can customize model parameters like context limits:
+
+```json
+{
+ "$schema": "https://opencode.ai/config.json",
+ "provider": {
+ "litellm": {
+ "npm": "@ai-sdk/openai-compatible",
+ "name": "LiteLLM",
+ "options": {
+ "baseURL": "http://localhost:4000/v1"
+ },
+ "models": {
+ "gpt-4": {
+ "name": "GPT-4",
+ "limit": {
+ "context": 128000,
+ "output": 4096
+ }
+ },
+ "claude-3-5-sonnet-20241022": {
+ "name": "Claude 3.5 Sonnet",
+ "limit": {
+ "context": 200000,
+ "output": 8192
+ }
+ }
+ }
+ }
+ }
+}
+```
+
+### Multi-Provider Setup
+
+You can configure multiple LiteLLM instances or mix with other providers:
+
+
+
+
+```json
+{
+ "$schema": "https://opencode.ai/config.json",
+ "provider": {
+ "litellm-prod": {
+ "npm": "@ai-sdk/openai-compatible",
+ "name": "LiteLLM Production",
+ "options": {
+ "baseURL": "https://your-prod-instance.com/v1"
+ },
+ "models": {
+ "gpt-4": {
+ "name": "GPT-4 (Production)"
+ }
+ }
+ },
+ "litellm-dev": {
+ "npm": "@ai-sdk/openai-compatible",
+ "name": "LiteLLM Development",
+ "options": {
+ "baseURL": "http://localhost:4000/v1"
+ },
+ "models": {
+ "gpt-4": {
+ "name": "GPT-4 (Development)"
+ }
+ }
+ }
+ }
+}
+```
+
+
+
+
+```json
+{
+ "$schema": "https://opencode.ai/config.json",
+ "provider": {
+ "litellm": {
+ "npm": "@ai-sdk/openai-compatible",
+ "name": "LiteLLM",
+ "options": {
+ "baseURL": "http://localhost:4000/v1"
+ },
+ "models": {
+ "gpt-4": {
+ "name": "GPT-4 via LiteLLM"
+ },
+ "claude-3-5-sonnet-20241022": {
+ "name": "Claude 3.5 Sonnet via LiteLLM"
+ }
+ }
+ },
+ "openai": {
+ "npm": "@ai-sdk/openai",
+ "name": "OpenAI Direct",
+ "models": {
+ "gpt-4o": {
+ "name": "GPT-4o (Direct)"
+ }
+ }
+ }
+ }
+}
+```
+
+
+
+
+## Example LiteLLM Configuration
+
+Here's an example LiteLLM `config.yaml` that works well with OpenCode:
+
+```yaml
+model_list:
+ # OpenAI models
+ - model_name: gpt-4
+ litellm_params:
+ model: openai/gpt-4
+ api_key: os.environ/OPENAI_API_KEY
+
+ - model_name: gpt-4o
+ litellm_params:
+ model: openai/gpt-4o
+ api_key: os.environ/OPENAI_API_KEY
+
+ # Anthropic models
+ - model_name: claude-3-5-sonnet-20241022
+ litellm_params:
+ model: anthropic/claude-3-5-sonnet-20241022
+ api_key: os.environ/ANTHROPIC_API_KEY
+
+ # DeepSeek models
+ - model_name: deepseek-chat
+ litellm_params:
+ model: deepseek/deepseek-chat
+ api_key: os.environ/DEEPSEEK_API_KEY
+```
+
+## Troubleshooting
+
+**OpenCode not connecting:**
+- Verify your LiteLLM proxy is running: `curl http://localhost:4000/health`
+- Check that the `baseURL` in your OpenCode config matches your LiteLLM instance
+- Ensure the provider name in `/connect` matches exactly with your config
+
+**Authentication errors:**
+- Verify your LiteLLM API key is correct
+- Check that your LiteLLM instance has authentication properly configured
+- Ensure your API key has access to the models you're trying to use
+
+**Model not found:**
+- Ensure the model names in OpenCode config match your LiteLLM `model_name` values
+- Check LiteLLM logs for detailed error messages
+- Verify the models are properly configured in your LiteLLM instance
+
+**Configuration not loading:**
+- Check the config file path and permissions
+- Validate JSON syntax using a JSON validator
+- Ensure the `$schema` URL is accessible
+
+## Tips
+
+- Add more models to the config as needed - they'll appear in `/models`
+- Use project-specific configs for different codebases with different model requirements
+- Monitor your LiteLLM proxy logs to see OpenCode requests in real-time
diff --git a/docs/my-website/img/a2a_agent_spend.png b/docs/my-website/img/a2a_agent_spend.png
new file mode 100644
index 00000000000..15ec769392a
Binary files /dev/null and b/docs/my-website/img/a2a_agent_spend.png differ
diff --git a/docs/my-website/img/a2a_trace_grouping.png b/docs/my-website/img/a2a_trace_grouping.png
new file mode 100644
index 00000000000..05130420aae
Binary files /dev/null and b/docs/my-website/img/a2a_trace_grouping.png differ
diff --git a/docs/my-website/img/okta_access_policies.png b/docs/my-website/img/okta_access_policies.png
new file mode 100644
index 00000000000..e09adc2ce7f
Binary files /dev/null and b/docs/my-website/img/okta_access_policies.png differ
diff --git a/docs/my-website/img/okta_authorization_server.png b/docs/my-website/img/okta_authorization_server.png
new file mode 100644
index 00000000000..bddb3e07a4a
Binary files /dev/null and b/docs/my-website/img/okta_authorization_server.png differ
diff --git a/docs/my-website/img/okta_client_credentials.png b/docs/my-website/img/okta_client_credentials.png
new file mode 100644
index 00000000000..a00a9f4657e
Binary files /dev/null and b/docs/my-website/img/okta_client_credentials.png differ
diff --git a/docs/my-website/img/okta_redirect_uri.png b/docs/my-website/img/okta_redirect_uri.png
new file mode 100644
index 00000000000..a1e58560c72
Binary files /dev/null and b/docs/my-website/img/okta_redirect_uri.png differ
diff --git a/docs/my-website/img/okta_security_api.png b/docs/my-website/img/okta_security_api.png
new file mode 100644
index 00000000000..7f9e218074c
Binary files /dev/null and b/docs/my-website/img/okta_security_api.png differ
diff --git a/docs/my-website/img/ui_granular_router_settings.png b/docs/my-website/img/ui_granular_router_settings.png
new file mode 100644
index 00000000000..6242679956c
Binary files /dev/null and b/docs/my-website/img/ui_granular_router_settings.png differ
diff --git a/docs/my-website/img/ui_spend_logs_settings.png b/docs/my-website/img/ui_spend_logs_settings.png
new file mode 100644
index 00000000000..334f5b1d93e
Binary files /dev/null and b/docs/my-website/img/ui_spend_logs_settings.png differ
diff --git a/docs/my-website/img/ui_tools.png b/docs/my-website/img/ui_tools.png
new file mode 100644
index 00000000000..6f4d0f87410
Binary files /dev/null and b/docs/my-website/img/ui_tools.png differ
diff --git a/docs/my-website/package-lock.json b/docs/my-website/package-lock.json
index 9af110096f4..419211cca02 100644
--- a/docs/my-website/package-lock.json
+++ b/docs/my-website/package-lock.json
@@ -14179,9 +14179,9 @@
"license": "MIT"
},
"node_modules/lodash-es": {
- "version": "4.17.21",
- "resolved": "https://registry.npmjs.org/lodash-es/-/lodash-es-4.17.21.tgz",
- "integrity": "sha512-mKnC+QJ9pWVzv+C4/U3rRsHapFfHvQFoFB92e52xeyGMcX6/OlIl78je1u8vePzYZSkkogMPJ2yjxxsb89cxyw==",
+ "version": "4.17.23",
+ "resolved": "https://registry.npmjs.org/lodash-es/-/lodash-es-4.17.23.tgz",
+ "integrity": "sha512-kVI48u3PZr38HdYz98UmfPnXl2DXrpdctLrFLCd3kOx1xUkOmpFPx7gCWWM5MPkL/fD8zb+Ph0QzjGFs4+hHWg==",
"license": "MIT"
},
"node_modules/lodash.debounce": {
@@ -20455,13 +20455,6 @@
"url": "https://opencollective.com/webpack"
}
},
- "node_modules/search-insights": {
- "version": "2.17.3",
- "resolved": "https://registry.npmjs.org/search-insights/-/search-insights-2.17.3.tgz",
- "integrity": "sha512-RQPdCYTa8A68uM2jwxoY842xDhvx3E5LFL1LxvxCNMev4o5mLuokczhzjAgGwUZBAmOKZknArSxLKmXtIi2AxQ==",
- "license": "MIT",
- "peer": true
- },
"node_modules/section-matter": {
"version": "1.0.0",
"resolved": "https://registry.npmjs.org/section-matter/-/section-matter-1.0.0.tgz",
diff --git a/docs/my-website/package.json b/docs/my-website/package.json
index e532f7c2cb5..4c3db680565 100644
--- a/docs/my-website/package.json
+++ b/docs/my-website/package.json
@@ -62,6 +62,7 @@
"gray-matter": "4.0.3",
"glob": ">=11.1.0",
"node-forge": ">=1.3.2",
- "mdast-util-to-hast": ">=13.2.1"
+ "mdast-util-to-hast": ">=13.2.1",
+ "lodash-es": ">=4.17.23"
}
}
\ No newline at end of file
diff --git a/docs/my-website/release_notes/v1.81.0/index.md b/docs/my-website/release_notes/v1.81.0/index.md
index 88ac240c614..e61d7d2d593 100644
--- a/docs/my-website/release_notes/v1.81.0/index.md
+++ b/docs/my-website/release_notes/v1.81.0/index.md
@@ -1,5 +1,5 @@
---
-title: "v1.81.0 - Claude Code - Web Search Across All Providers"
+title: "v1.81.0-stable - Claude Code - Web Search Across All Providers"
slug: "v1-81-0"
date: 2026-01-18T10:00:00
authors:
@@ -27,7 +27,7 @@ import TabItem from '@theme/TabItem';
docker run \
-e STORE_MODEL_IN_DB=True \
-p 4000:4000 \
-docker.litellm.ai/berriai/litellm:v1.81.0.rc.1
+docker.litellm.ai/berriai/litellm:v1.81.0-stable
```
@@ -62,7 +62,7 @@ This means you can now use Claude Code's web search tool with any provider, not
Proxy Admins can configure web search interception in their LiteLLM proxy config to enable this capability for their teams using Claude Code with Bedrock, Azure, or any other supported provider.
-[**Learn more →**](../../docs/tutorials/claude_code_websearch.md)
+[**Learn more →**](https://docs.litellm.ai/docs/tutorials/claude_code_websearch)
---
diff --git a/docs/my-website/release_notes/v1.81.3-stable/index.md b/docs/my-website/release_notes/v1.81.3-stable/index.md
new file mode 100644
index 00000000000..22b6f43deef
--- /dev/null
+++ b/docs/my-website/release_notes/v1.81.3-stable/index.md
@@ -0,0 +1,423 @@
+---
+title: "v1.81.3-stable - Performance - 25% CPU Usage Reduction"
+slug: "v1-81-3"
+date: 2026-01-26T10:00:00
+authors:
+ - name: Krrish Dholakia
+ title: CEO, LiteLLM
+ url: https://www.linkedin.com/in/krish-d/
+ image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
+ - name: Ishaan Jaff
+ title: CTO, LiteLLM
+ url: https://www.linkedin.com/in/reffajnaahsi/
+ image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
+hide_table_of_contents: false
+---
+
+import Image from '@theme/IdealImage';
+import Tabs from '@theme/Tabs';
+import TabItem from '@theme/TabItem';
+
+## Deploy this version
+
+
+
+
+``` showLineNumbers title="docker run litellm"
+docker run \
+-e STORE_MODEL_IN_DB=True \
+-p 4000:4000 \
+docker.litellm.ai/berriai/litellm:v1.81.3.rc.2
+```
+
+
+
+
+
+``` showLineNumbers title="pip install litellm"
+pip install litellm==1.81.3.rc.2
+```
+
+
+
+
+---
+
+## New Models / Updated Models
+
+### New Model Support
+
+| Provider | Model | Context Window | Input ($/1M tokens) | Output ($/1M tokens) | Deprecation Date |
+| -------- | ----- | -------------- | ------------------- | -------------------- | ---------------- |
+| OpenAI | `gpt-audio`, `gpt-audio-2025-08-28` | 128K | $32/1M audio tokens, $2.5/1M text tokens | $64/1M audio tokens, $10/1M text tokens | - |
+| OpenAI | `gpt-audio-mini`, `gpt-audio-mini-2025-08-28` | 128K | $10/1M audio tokens, $0.6/1M text tokens | $20/1M audio tokens, $2.4/1M text tokens | - |
+| Deepinfra, Vertex AI, Google AI Studio, OpenRouter, Vercel AI Gateway | `gemini-2.0-flash-001`, `gemini-2.0-flash` | - | - | - | 2026-03-31 |
+| Groq | `openai/gpt-oss-120b` | 131K | 0.075/1M cache read | 0.6/1M output tokens | - |
+| Groq | `groq/openai/gpt-oss-20b` | 131K | 0.0375/1M cache read, $0.075/1M text tokens | 0.3/1M output tokens | - |
+| Vertex AI | `gemini-2.5-computer-use-preview-10-2025` | 128K | $1.25 | $10 | - |
+| Azure AI | `claude-haiku-4-5` | $1.25/1M cache read, $2/1M cache read above 1 hr, $0.1/1M text tokens | $5/1M output tokens | - |
+| Azure AI | `claude-sonnet-4-5` | $3.75/1M cache read, $6/1M cache read above 1 hr, $3/1M text tokens | $15/1M output tokens | - |
+| Azure AI | `claude-opus-4-5` | $6.25/1M cache read, $10/1M cache read above 1 hr, $0.5/1M text tokens | $25/1M output tokens | - |
+| Azure AI | `claude-opus-4-1` | $18.75/1M cache read, $30/1M cache read above 1 hr, $1.5/1M text tokens | $75/1M output tokens | - |
+
+### Features
+
+- **[OpenAI](../../docs/providers/openai)**
+ - Add gpt-audio and gpt-audio-mini models to pricing - [PR #19509](https://github.com/BerriAI/litellm/pull/19509)
+ - correct audio token costs for gpt-4o-audio-preview models - [PR #19500](https://github.com/BerriAI/litellm/pull/19500)
+ - Limit stop sequence as per openai spec (ensures JetBrains IDE compatibility) - [PR #19562](https://github.com/BerriAI/litellm/pull/19562)
+
+- **[VertexAI](../../docs/providers/vertex)**
+ - Docs - Google Workload Identity Federation (WIF) support - [PR #19320](https://github.com/BerriAI/litellm/pull/19320)
+
+- **[Agentcore](../../docs/providers/bedrock_agentcore)**
+ - Fixes streaming issues with AWS Bedrock AgentCore where responses would stop after the first chunk, particularly affecting OAuth-enabled agents - [PR #17141](https://github.com/BerriAI/litellm/pull/17141)
+
+- **[Chatgpt](../../docs/providers/chatgpt)**
+ - Adds support for calling chatgpt subscription via LiteLLM - [PR #19030](https://github.com/BerriAI/litellm/pull/19030)
+ - Adds responses API bridge support for chatgpt subscription provider - [PR #19030](https://github.com/BerriAI/litellm/pull/19030)
+
+- **[Bedrock](../../docs/providers/bedrock)**
+ - support for output format for bedrock invoke via v1/messages - [PR #19560](https://github.com/BerriAI/litellm/pull/19560)
+
+- **[Azure](../../docs/providers/azure/azure)**
+ - Add support for Azure OpenAI v1 API - [PR #19313](https://github.com/BerriAI/litellm/pull/19313)
+ - preserve content_policy_violation details for images (#19328) - [PR #19372](https://github.com/BerriAI/litellm/pull/19372)
+ - Support OpenAI-format nested tool definitions for Responses API - [PR #19526](https://github.com/BerriAI/litellm/pull/19526)
+
+- **Gemini([Vertex AI](../../docs/providers/vertex), [Google AI Studio](../../docs/providers/gemini))**
+ - use responseJsonSchema for Gemini 2.0+ models - [PR #19314](https://github.com/BerriAI/litellm/pull/19314)
+
+- **[Volcengine](../../docs/providers/volcano)**
+ - Support Volcengine responses api - [PR #18508](https://github.com/BerriAI/litellm/pull/18508)
+
+- **[Anthropic](../../docs/providers/anthropic)**
+ - Add Support for calling Claude Code Max subscriptions via LiteLLM - [PR #19453](https://github.com/BerriAI/litellm/pull/19453)
+ - Add Structured output for /v1/messages with Anthropic API, Azure Anthropic API, Bedrock Converse - [PR #19545](https://github.com/BerriAI/litellm/pull/19545)
+
+- **[Brave Search](../../docs/search/brave)**
+ - New Search provider - [PR #19433](https://github.com/BerriAI/litellm/pull/19433)
+
+- **Sarvam ai**
+ - Add support for new sarvam models - [PR #19479](https://github.com/BerriAI/litellm/pull/19479)
+
+- **[GMI](../../docs/providers/gmi)**
+ - add GMI Cloud provider support - [PR #19376](https://github.com/BerriAI/litellm/pull/19376)
+
+
+### Bug Fixes
+
+- **[Anthropic](../../docs/providers/anthropic)**
+ - Fix anthropic-beta sent client side being overridden instead of appended to - [PR #19343](https://github.com/BerriAI/litellm/pull/19343)
+ - Filter out unsupported fields from JSON schema for Anthropic's output_format API - [PR #19482](https://github.com/BerriAI/litellm/pull/19482)
+
+- **[Bedrock](../../docs/providers/bedrock)**
+ - Expose stability models via /image_edits endpoint and ensure proper request transformation - [PR #19323](https://github.com/BerriAI/litellm/pull/19323)
+ - Claude Code x Bedrock Invoke fails with advanced-tool-use-2025-11-20 - [PR #19373](https://github.com/BerriAI/litellm/pull/19373)
+ - deduplicate tool calls in assistant history - [PR #19324](https://github.com/BerriAI/litellm/pull/19324)
+ - fix: correct us.anthropic.claude-opus-4-5 In-region pricing - [PR #19310](https://github.com/BerriAI/litellm/pull/19310)
+ - Fix request validation errors when using Claude 4 via bedrock invoke - [PR #19381](https://github.com/BerriAI/litellm/pull/19381)
+ - Handle thinking with tool calls for Claude 4 models - [PR #19506](https://github.com/BerriAI/litellm/pull/19506)
+ - correct streaming choice index for tool calls - [PR #19506](https://github.com/BerriAI/litellm/pull/19506)
+
+- **[Ollama](../../docs/providers/ollama)**
+ - Fix tool call errors due with improved message extraction - [PR #19369](https://github.com/BerriAI/litellm/pull/19369)
+
+- **[VertexAI](../../docs/providers/vertex)**
+ - Removed optional vertex_count_tokens_location param before request is sent to vertex - [PR #19359](https://github.com/BerriAI/litellm/pull/19359)
+
+- **Gemini([Vertex AI](../../docs/providers/vertex), [Google AI Studio](../../docs/providers/gemini))**
+ - Supports setting media_resolution and fps parameters on each video file, when using Gemini video understanding - [PR #19273](https://github.com/BerriAI/litellm/pull/19273)
+ - handle reasoning_effort as dict from OpenAI Agents SDK - [PR #19419](https://github.com/BerriAI/litellm/pull/19419)
+ - add file content support in tool results - [PR #19416](https://github.com/BerriAI/litellm/pull/19416)
+
+- **[Azure](../../docs/providers/azure_ai)**
+ - Fix Azure AI costs for Anthropic models - [PR #19530](https://github.com/BerriAI/litellm/pull/19530)
+
+- **[Giga Chat](../../docs/providers/gigachat)**
+ - Add tool choice mapping - [PR #19645](https://github.com/BerriAI/litellm/pull/19645)
+---
+
+## AI API Endpoints (LLMs, MCP, Agents)
+
+### Features
+
+- **[Files API](../../docs/files_endpoints)**
+ - Add managed files support when load_balancing is True - [PR #19338](https://github.com/BerriAI/litellm/pull/19338)
+
+- **[Claude Plugin Marketplace](../../docs/tutorials/claude_code_plugin_marketplace)**
+ - Add self hosted Claude Code Plugin Marketplace - [PR #19378](https://github.com/BerriAI/litellm/pull/19378)
+
+- **[MCP](../../docs/mcp)**
+ - Add MCP Protocol version 2025-11-25 support - [PR #19379](https://github.com/BerriAI/litellm/pull/19379)
+ - Log MCP tool calls and list tools in the LiteLLM Spend Logs table for easier debugging - [PR #19469](https://github.com/BerriAI/litellm/pull/19469)
+
+- **[Vertex AI](../../docs/providers/vertex)**
+ - Ensure only anthropic betas are forwarded down to LLM API (by default) - [PR #19542](https://github.com/BerriAI/litellm/pull/19542)
+ - Allow overriding to support forwarding incoming headers are forwarded down to target - [PR #19524](https://github.com/BerriAI/litellm/pull/19524)
+
+- **[Chat/Completions](../../docs/completion/input)**
+ - Add MCP tools response to chat completions - [PR #19552](https://github.com/BerriAI/litellm/pull/19552)
+ - Add custom vertex ai finish reasons to the output - [PR #19558](https://github.com/BerriAI/litellm/pull/19558)
+ - Return MCP execution in /chat/completions before model output during streaming - [PR #19623](https://github.com/BerriAI/litellm/pull/19623)
+
+### Bugs
+
+- **[Responses API](../../docs/response_api)**
+ - Fix duplicate messages during MCP streaming tool execution - [PR #19317](https://github.com/BerriAI/litellm/pull/19317)
+ - Fix pickle error when using OpenAI's Responses API with stream=True and tool_choice of type allowed_tools (an OpenAI-native parameter) - [PR #17205](https://github.com/BerriAI/litellm/pull/17205)
+ - stream tool call events for non-openai models - [PR #19368](https://github.com/BerriAI/litellm/pull/19368)
+ - preserve tool output ordering for gemini in responses bridge - [PR #19360](https://github.com/BerriAI/litellm/pull/19360)
+ - Add ID caching to prevent ID mismatch text-start and text-delta - [PR #19390](https://github.com/BerriAI/litellm/pull/19390)
+ - Include output_item, reasoning_summary_Text_done and reasoning_summary_part_done events for non-openai models - [PR #19472](https://github.com/BerriAI/litellm/pull/19472)
+
+- **[Chat/Completions](../../docs/completion/input)**
+ - fix: drop_params not dropping prompt_cache_key for non-OpenAI providers - [PR #19346](https://github.com/BerriAI/litellm/pull/19346)
+
+- **[Realtime API](../../docs/realtime)**
+ - disable SSL for ws:// WebSocket connections - [PR #19345](https://github.com/BerriAI/litellm/pull/19345)
+
+- **[Generate Content](../../docs/generateContent)**
+ - Log actual user input when google genai/vertex endpoints are called client-side - [PR #19156](https://github.com/BerriAI/litellm/pull/19156)
+
+- **[/messages/count_tokens Anthropic Token Counting](../../docs/anthropic_count_tokens)**
+ - ensure it works for Anthropic, Azure AI Anthropic on AI Gateway - [PR #19432](https://github.com/BerriAI/litellm/pull/19432)
+
+- **[MCP](../../docs/mcp)**
+ - forward static_headers to MCP servers - [PR #19366](https://github.com/BerriAI/litellm/pull/19366)
+
+- **[Batch API](../../docs/batches)**
+ - Fix: generation config empty for batch - [PR #19556](https://github.com/BerriAI/litellm/pull/19556)
+
+- **[Pass Through Endpoints](../../docs/proxy/pass_through)**
+ - Always reupdate registry - [PR #19420](https://github.com/BerriAI/litellm/pull/19420)
+---
+
+## Management Endpoints / UI
+
+### Features
+
+- **Cost Estimator**
+ - Fix model dropdown - [PR #19529](https://github.com/BerriAI/litellm/pull/19529)
+
+- **Claude Code Plugins**
+ - Allow Adding Claude Code Plugins via UI - [PR #19387](https://github.com/BerriAI/litellm/pull/19387)
+
+- **Guardrails**
+ - New Policy management UI - [PR #19668](https://github.com/BerriAI/litellm/pull/19668)
+ - Allow adding policies on Keys/Teams + Viewing on Info panels - [PR #19688](https://github.com/BerriAI/litellm/pull/19688)
+
+- **General**
+ - respects custom authentication header override - [PR #19276](https://github.com/BerriAI/litellm/pull/19276)
+
+- **Playground**
+ - Button to Fill Custom API Base - [PR #19440](https://github.com/BerriAI/litellm/pull/19440)
+ - display mcp output on the play ground - [PR #19553](https://github.com/BerriAI/litellm/pull/19553)
+
+- **Models**
+ - Paginate /v2/models/info - [PR #19521](https://github.com/BerriAI/litellm/pull/19521)
+ - All Model Tab Pagination - [PR #19525](https://github.com/BerriAI/litellm/pull/19525)
+ - Adding Optional scope Param to /models - [PR #19539](https://github.com/BerriAI/litellm/pull/19539)
+ - Model Search - [PR #19622](https://github.com/BerriAI/litellm/pull/19622)
+ - Filter by Model ID and Team ID - [PR #19713](https://github.com/BerriAI/litellm/pull/19713)
+
+- **MCP Servers**
+ - MCP Tools Tab Resetting to Overview - [PR #19468](https://github.com/BerriAI/litellm/pull/19468)
+
+- **Organizations**
+ - Prevent org admin from creating a new user with proxy_admin permissions - [PR #19296](https://github.com/BerriAI/litellm/pull/19296)
+ - Edit Page: Reusable Model Select - [PR #19601](https://github.com/BerriAI/litellm/pull/19601)
+
+- **Teams**
+ - Reusable Model Select - [PR #19543](https://github.com/BerriAI/litellm/pull/19543)
+ - [Fix] Team Update with Organization having All Proxy Models - [PR #19604](https://github.com/BerriAI/litellm/pull/19604)
+
+- **Logs**
+ - Include tool arguments in spend logs table - [PR #19640](https://github.com/BerriAI/litellm/pull/19640)
+
+- **Fallbacks / Loadbalancing**
+ - New fallbacks modal - [PR #19673](https://github.com/BerriAI/litellm/pull/19673)
+ - Set fallbacks/loadbalancing by team/key - [PR #19686](https://github.com/BerriAI/litellm/pull/19686)
+
+### Bugs
+
+- **Playground**
+ - increase model selector width in playground Compare view - [PR #19423](https://github.com/BerriAI/litellm/pull/19423)
+
+- **Virtual Keys**
+ - Sorting Shows Incorrect Entries - [PR #19534](https://github.com/BerriAI/litellm/pull/19534)
+
+- **General**
+ - UI 404 error when SERVER_ROOT_PATH is set - [PR #19467](https://github.com/BerriAI/litellm/pull/19467)
+ - Redirect to ui/login on expired JWT - [PR #19687](https://github.com/BerriAI/litellm/pull/19687)
+
+- **SSO**
+ - Fix SSO user roles not updating for existing users - [PR #19621](https://github.com/BerriAI/litellm/pull/19621)
+
+- **Guardrails**
+ - ensure guardrail patterns persist on edit and mode toggle - [PR #19265](https://github.com/BerriAI/litellm/pull/19265)
+---
+
+## AI Integrations
+
+### Logging
+
+- **General Logging**
+ - prevent printing duplicate StandardLoggingPayload logs - [PR #19325](https://github.com/BerriAI/litellm/pull/19325)
+ - Fix: log duplication when json_logs is enabled - [PR #19705](https://github.com/BerriAI/litellm/pull/19705)
+- **Langfuse OTEL**
+ - ignore service logs and fix callback shadowing - [PR #19298](https://github.com/BerriAI/litellm/pull/19298)
+- **Langfuse**
+ - Send litellm_trace_id - [PR #19528](https://github.com/BerriAI/litellm/pull/19528)
+ - Add Langfuse mock mode for testing without API calls - [PR #19676](https://github.com/BerriAI/litellm/pull/19676)
+- **GCS Bucket**
+ - prevent unbounded queue growth due to slow API calls - [PR #19297](https://github.com/BerriAI/litellm/pull/19297)
+ - Add GCS mock mode for testing without API calls - [PR #19683](https://github.com/BerriAI/litellm/pull/19683)
+- **Responses API Logging**
+ - Fix pydantic serialization error - [PR #19486](https://github.com/BerriAI/litellm/pull/19486)
+- **Arize Phoenix**
+ - add openinference span kinds to arize phoenix - [PR #19267](https://github.com/BerriAI/litellm/pull/19267)
+- **Prometheus**
+ - Added new prometheus metrics for user count and team count - [PR #19520](https://github.com/BerriAI/litellm/pull/19520)
+
+### Guardrails
+
+- **Bedrock Guardrails**
+ - Ensure post_call guardrail checks input+output - [PR #19151](https://github.com/BerriAI/litellm/pull/19151)
+- **Prompt Security**
+ - fixing prompt-security's guardrail implementation - [PR #19374](https://github.com/BerriAI/litellm/pull/19374)
+- **Presidio**
+ - Fixes crash in Presidio Guardrail when running in background threads (logging_hook) - [PR #19714](https://github.com/BerriAI/litellm/pull/19714)
+- **Pillar Security**
+ - Migrate Pillar Security to Generic Guardrail API - [PR #19364](https://github.com/BerriAI/litellm/pull/19364)
+- **Policy Engine**
+ - New LiteLLM Policy engine - create policies to manage guardrails, conditions - permissions per Key, Team - [PR #19612](https://github.com/BerriAI/litellm/pull/19612)
+- **General**
+ - add case-insensitive support for guardrail mode and actions - [PR #19480](https://github.com/BerriAI/litellm/pull/19480)
+
+### Prompt Management
+
+- **General**
+ - fix prompt info lookup and delete using correct IDs - [PR #19358](https://github.com/BerriAI/litellm/pull/19358)
+
+### Secret Manager
+
+- **AWS Secret Manager**
+ - ensure auto-rotation updates existing AWS secret instead of creating new one - [PR #19455](https://github.com/BerriAI/litellm/pull/19455)
+- **Hashicorp Vault**
+ - Ensure key rotations work with Vault - [PR #19634](https://github.com/BerriAI/litellm/pull/19634)
+
+---
+
+## Spend Tracking, Budgets and Rate Limiting
+
+- **Pricing Updates**
+ - Add openai/dall-e base pricing entries - [PR #19133](https://github.com/BerriAI/litellm/pull/19133)
+ - Add `input_cost_per_video_per_second` in ModelInfoBase - [PR #19398](https://github.com/BerriAI/litellm/pull/19398)
+
+---
+
+## Performance / Loadbalancing / Reliability improvements
+
+
+- **General**
+ - Fix date overflow/division by zero in proxy utils - [PR #19527](https://github.com/BerriAI/litellm/pull/19527)
+ - Fix in-flight request termination on SIGTERM when health-check runs in a separate process - [PR #19427](https://github.com/BerriAI/litellm/pull/19427)
+ - Fix Pass through routes to work with server root path - [PR #19383](https://github.com/BerriAI/litellm/pull/19383)
+ - Fix logging error for stop iteration - [PR #19649](https://github.com/BerriAI/litellm/pull/19649)
+ - prevent retrying 4xx client errors - [PR #19275](https://github.com/BerriAI/litellm/pull/19275)
+ - add better error handling for misconfig on health check - [PR #19441](https://github.com/BerriAI/litellm/pull/19441)
+
+- **Router**
+ - Fix Azure RPM calculation formula - [PR #19513](https://github.com/BerriAI/litellm/pull/19513)
+ - Persist scheduler request queue to redis - [PR #19304](https://github.com/BerriAI/litellm/pull/19304)
+ - pass search_tools to Router during DB-triggered initialization - [PR #19388](https://github.com/BerriAI/litellm/pull/19388)
+ - Fixed PromptCachingCache to correctly handle messages where cache_control is a sibling key of string content - [PR #19266](https://github.com/BerriAI/litellm/pull/19266)
+
+- **Memory Leaks/OOM**
+ - prevent OOM with nested $defs in tool schemas - [PR #19112](https://github.com/BerriAI/litellm/pull/19112)
+ - fix: HTTP client memory leaks in Presidio, OpenAI, and Gemini - [PR #19190](https://github.com/BerriAI/litellm/pull/19190)
+
+- **Non root**
+ - fix logfile and pidfile of supervisor for non root environment - [PR #17267](https://github.com/BerriAI/litellm/pull/17267)
+ - resolve Read-only file system error in non-root images - [PR #19449](https://github.com/BerriAI/litellm/pull/19449)
+
+- **Dockerfile**
+ - Redis Semantic Caching - add missing redisvl dependency to requirements.txt - [PR #19417](https://github.com/BerriAI/litellm/pull/19417)
+ - Bump OTEL versions to support a2a dependency - resolves modulenotfounderror for Microsoft Agents by @Harshit28j in #18991
+
+- **DB**
+ - Handle PostgreSQL cached plan errors during rolling deployments - [PR #19424](https://github.com/BerriAI/litellm/pull/19424)
+
+- **Timeouts**
+ - Fix: total timeout is not respected - [PR #19389](https://github.com/BerriAI/litellm/pull/19389)
+
+- **SDK**
+ - Field-Existence Checks to Type Classes to Prevent Attribute Errors - [PR #18321](https://github.com/BerriAI/litellm/pull/18321)
+ - add google-cloud-aiplatform as optional dependency with clear error message - [PR #19437](https://github.com/BerriAI/litellm/pull/19437)
+ - Make grpc dependency optional - [PR #19447](https://github.com/BerriAI/litellm/pull/19447)
+ - Add support for retry policies - [PR #19645](https://github.com/BerriAI/litellm/pull/19645)
+
+- **Performance**
+ - Cut chat_completion latency by ~21% by reducing pre-call processing time - [PR #19535](https://github.com/BerriAI/litellm/pull/19535)
+ - Optimize strip_trailing_slash with O(1) index check - [PR #19679](https://github.com/BerriAI/litellm/pull/19679)
+ - Optimize use_custom_pricing_for_model with set intersection - [PR #19677](https://github.com/BerriAI/litellm/pull/19677)
+ - perf: skip pattern_router.route() for non-wildcard models - [PR #19664](https://github.com/BerriAI/litellm/pull/19664)
+ - perf: Add LRU caching to get_model_info for faster cost lookups - [PR #19606](https://github.com/BerriAI/litellm/pull/19606)
+
+---
+
+## General Proxy Improvements
+
+### Doc Improvements
+ - new tutorial for adding MCPs to Cursor via LiteLLM - [PR #19317](https://github.com/BerriAI/litellm/pull/19317)
+ - fix vertex_region to vertex_location in Vertex AI pass-through docs - [PR #19380](https://github.com/BerriAI/litellm/pull/19380)
+ - clarify Gemini and Vertex AI model prefix in json file - [PR #19443](https://github.com/BerriAI/litellm/pull/19443)
+ - update Claude Code integration guides - [PR #19415](https://github.com/BerriAI/litellm/pull/19415)
+ - adjust opencode tutorial - [PR #19605](https://github.com/BerriAI/litellm/pull/19605)
+ - add spend-queue-troubleshooting docs - [PR #19659](https://github.com/BerriAI/litellm/pull/19659)
+ - docs: add litellm-enterprise requirement for managed files - [PR #19689](https://github.com/BerriAI/litellm/pull/19689)
+
+### Helm
+ - Add support for keda in helm chart - [PR #19337](https://github.com/BerriAI/litellm/pull/19337)
+ - sync Helm chart version with LiteLLM release version - [PR #19438](https://github.com/BerriAI/litellm/pull/19438)
+ - Enable PreStop hook configuration in values.yaml - [PR #19613](https://github.com/BerriAI/litellm/pull/19613)
+
+### General
+ - Add health check scripts and parallel execution support - [PR #19295](https://github.com/BerriAI/litellm/pull/19295)
+
+
+---
+
+## New Contributors
+
+
+* @dushyantzz made their first contribution in [PR #19158](https://github.com/BerriAI/litellm/pull/19158)
+* @obod-mpw made their first contribution in [PR #19133](https://github.com/BerriAI/litellm/pull/19133)
+* @msexxeta made their first contribution in [PR #19030](https://github.com/BerriAI/litellm/pull/19030)
+* @rsicart made their first contribution in [PR #19337](https://github.com/BerriAI/litellm/pull/19337)
+* @cluebbehusen made their first contribution in [PR #19311](https://github.com/BerriAI/litellm/pull/19311)
+* @Lucky-Lodhi2004 made their first contribution in [PR #19315](https://github.com/BerriAI/litellm/pull/19315)
+* @binbandit made their first contribution in [PR #19324](https://github.com/BerriAI/litellm/pull/19324)
+* @flex-myeonghyeon made their first contribution in [PR #19381](https://github.com/BerriAI/litellm/pull/19381)
+* @Lrakotoson made their first contribution in [PR #18321](https://github.com/BerriAI/litellm/pull/18321)
+* @bensi94 made their first contribution in [PR #18787](https://github.com/BerriAI/litellm/pull/18787)
+* @victorigualada made their first contribution in [PR #19368](https://github.com/BerriAI/litellm/pull/19368)
+* @VedantMadane made their first contribution in #19266
+* @stiyyagura0901 made their first contribution in #19276
+* @kamilio made their first contribution in [PR #19447](https://github.com/BerriAI/litellm/pull/19447)
+* @jonathansampson made their first contribution in [PR #19433](https://github.com/BerriAI/litellm/pull/19433)
+* @rynecarbone made their first contribution in [PR #19416](https://github.com/BerriAI/litellm/pull/19416)
+* @jayy-77 made their first contribution in #19366
+* @davida-ps made their first contribution in [PR #19374](https://github.com/BerriAI/litellm/pull/19374)
+* @joaodinissf made their first contribution in [PR #19506](https://github.com/BerriAI/litellm/pull/19506)
+* @ecao310 made their first contribution in [PR #19520](https://github.com/BerriAI/litellm/pull/19520)
+* @mpcusack-altos made their first contribution in [PR #19577](https://github.com/BerriAI/litellm/pull/19577)
+* @milan-berri made their first contribution in [PR #19602](https://github.com/BerriAI/litellm/pull/19602)
+* @xqe2011 made their first contribution in #19621
+
+---
+
+## Full Changelog
+
+**[View complete changelog on GitHub](https://github.com/BerriAI/litellm/releases/tag/v1.81.3.rc)**
diff --git a/docs/my-website/release_notes/v1.81.6.md b/docs/my-website/release_notes/v1.81.6.md
new file mode 100644
index 00000000000..ef19276f2cf
--- /dev/null
+++ b/docs/my-website/release_notes/v1.81.6.md
@@ -0,0 +1,384 @@
+---
+title: "v1.81.6 - Logs v2 with Tool Call Tracing"
+slug: "v1-81-6"
+date: 2026-01-31T00:00:00
+authors:
+ - name: Krrish Dholakia
+ title: CEO, LiteLLM
+ url: https://www.linkedin.com/in/krish-d/
+ image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
+ - name: Ishaan Jaff
+ title: CTO, LiteLLM
+ url: https://www.linkedin.com/in/reffajnaahsi/
+ image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
+hide_table_of_contents: false
+---
+
+## Deploy this version
+
+import Tabs from '@theme/Tabs';
+import TabItem from '@theme/TabItem';
+import Image from '@theme/IdealImage';
+
+
+
+
+```bash
+docker run \
+-e STORE_MODEL_IN_DB=True \
+-p 4000:4000 \
+docker.litellm.ai/berriai/litellm:main-v1.81.6
+```
+
+
+
+
+```bash
+pip install litellm==1.81.6
+```
+
+
+
+
+## Key Highlights
+
+Logs View v2 with Tool Call Tracing - Redesigned logs interface with side panel, structured tool visualization, and error message search for faster debugging.
+
+Let's dive in.
+
+### Logs View v2 with Tool Call Tracing
+
+This release introduces comprehensive tool call tracing through LiteLLM's redesigned Logs View v2, enabling developers to debug and monitor AI agent workflows in production environments seamlessly.
+
+This means you can now onboard use cases like tracing complex multi-step agent interactions, debugging tool execution failures, and monitoring MCP server calls while maintaining full visibility into request/response payloads with syntax highlighting.
+
+Developers can access the new Logs View through LiteLLM's UI to inspect tool calls in structured format, search logs by error messages or request patterns, and correlate agent activities across sessions with collapsible side panel views.
+
+{/* TODO: Add image from Slack (group_7219.png) - save as logs_v2_tool_tracing.png */}
+{/* */}
+
+[Get Started](../../docs/proxy/ui_logs)
+
+## New Models / Updated Models
+
+#### New Model Support
+
+| Provider | Model | Context Window | Input ($/1M tokens) | Output ($/1M tokens) | Features |
+| -------- | ----- | -------------- | ------------------- | -------------------- | -------- |
+| AWS Bedrock | `amazon.nova-2-pro-preview-20251202-v1:0` | 1M | $2.19 | $17.50 | Chat completions, vision, video, PDF, function calling, prompt caching, reasoning |
+| Google Vertex AI | `gemini-robotics-er-1.5-preview` | 1M | $0.30 | $2.50 | Chat completions, multimodal (text, image, video, audio), function calling, reasoning |
+| OpenRouter | `openrouter/xiaomi/mimo-v2-flash` | 262K | $0.09 | $0.29 | Chat completions, function calling, reasoning |
+| OpenRouter | `openrouter/moonshotai/kimi-k2.5` | - | - | - | Chat completions |
+| OpenRouter | `openrouter/z-ai/glm-4.7` | 202K | $0.40 | $1.50 | Chat completions, vision, function calling, reasoning |
+
+#### Features
+
+- **[AWS Bedrock](../../docs/providers/bedrock)**
+ - Messages API Bedrock Converse caching and PDF support - [PR #19785](https://github.com/BerriAI/litellm/pull/19785)
+ - Translate advanced-tool-use to Bedrock-specific headers for Claude Opus 4.5 - [PR #19841](https://github.com/BerriAI/litellm/pull/19841)
+ - Support tool search header translation for Sonnet 4.5 - [PR #19871](https://github.com/BerriAI/litellm/pull/19871)
+ - Filter unsupported beta headers for AWS Bedrock Invoke API - [PR #19877](https://github.com/BerriAI/litellm/pull/19877)
+ - Nova grounding improvements - [PR #19598](https://github.com/BerriAI/litellm/pull/19598), [PR #20159](https://github.com/BerriAI/litellm/pull/20159)
+
+- **[Anthropic](../../docs/providers/anthropic)**
+ - Remove explicit cache_control null in tool_result content - [PR #19919](https://github.com/BerriAI/litellm/pull/19919)
+ - Fix tool handling - [PR #19805](https://github.com/BerriAI/litellm/pull/19805)
+
+- **[Google Gemini / Vertex AI](../../docs/providers/gemini)**
+ - Add Gemini Robotics-ER 1.5 preview support - [PR #19845](https://github.com/BerriAI/litellm/pull/19845)
+ - Support file retrieval in GoogleAIStudioFilesHandle - [PR #20018](https://github.com/BerriAI/litellm/pull/20018)
+ - Add /delete endpoint support - [PR #20055](https://github.com/BerriAI/litellm/pull/20055)
+ - Add custom_llm_provider as gemini translation - [PR #19988](https://github.com/BerriAI/litellm/pull/19988)
+ - Subtract implicit cached tokens from text_tokens for correct cost calculation - [PR #19775](https://github.com/BerriAI/litellm/pull/19775)
+ - Remove unsupported prompt-caching-scope-2026-01-05 header for vertex ai - [PR #20058](https://github.com/BerriAI/litellm/pull/20058)
+ - Add disable flag for anthropic gemini cache translation - [PR #20052](https://github.com/BerriAI/litellm/pull/20052)
+ - Convert image URLs to base64 in tool messages for Anthropic on Vertex AI - [PR #19896](https://github.com/BerriAI/litellm/pull/19896)
+
+- **[xAI](../../docs/providers/xai)**
+ - Add grok reasoning content support - [PR #19850](https://github.com/BerriAI/litellm/pull/19850)
+ - Add websearch params support for Responses API - [PR #19915](https://github.com/BerriAI/litellm/pull/19915)
+ - Add routing of xai chat completions to responses when web search options is present - [PR #20051](https://github.com/BerriAI/litellm/pull/20051)
+ - Correct cached token cost calculation - [PR #19772](https://github.com/BerriAI/litellm/pull/19772)
+
+- **[Azure OpenAI](../../docs/providers/azure)**
+ - Use generic cost calculator for audio token pricing - [PR #19771](https://github.com/BerriAI/litellm/pull/19771)
+ - Allow tool_choice for Azure GPT-5 chat models - [PR #19813](https://github.com/BerriAI/litellm/pull/19813)
+ - Set gpt-5.2-codex mode to responses for Azure and OpenRouter - [PR #19770](https://github.com/BerriAI/litellm/pull/19770)
+
+- **[OpenAI](../../docs/providers/openai)**
+ - Fix max_input_tokens for gpt-5.2-codex - [PR #20009](https://github.com/BerriAI/litellm/pull/20009)
+ - Fix gpt-image-1.5 cost calculation not including output image tokens - [PR #19515](https://github.com/BerriAI/litellm/pull/19515)
+
+- **[Hosted VLLM](../../docs/providers/vllm)**
+ - Support thinking parameter in anthropic_messages() and .completion() - [PR #19787](https://github.com/BerriAI/litellm/pull/19787)
+ - Route through base_llm_http_handler to support ssl_verify - [PR #19893](https://github.com/BerriAI/litellm/pull/19893)
+ - Fix vllm embedding format - [PR #20056](https://github.com/BerriAI/litellm/pull/20056)
+
+- **[OCI GenAI](../../docs/providers/oci)**
+ - Serialize imageUrl as object for OCI GenAI API - [PR #19661](https://github.com/BerriAI/litellm/pull/19661)
+
+- **[Volcengine](../../docs/providers/volcano)**
+ - Add context for volcengine models (deepseek-v3-2, glm-4-7, kimi-k2-thinking) - [PR #19335](https://github.com/BerriAI/litellm/pull/19335)
+
+- **[Chinese Providers](../../docs/providers/)**
+ - Add prompt caching and reasoning support for MiniMax, GLM, Xiaomi - [PR #19924](https://github.com/BerriAI/litellm/pull/19924)
+
+- **[Vercel AI Gateway](../../docs/providers/vercel_ai_gateway)**
+ - Add embeddings support - [PR #19660](https://github.com/BerriAI/litellm/pull/19660)
+
+### Bug Fixes
+
+- **[Google](../../docs/providers/gemini)**
+ - Fix gemini-robotics-er-1.5-preview entry - [PR #19974](https://github.com/BerriAI/litellm/pull/19974)
+
+- **General**
+ - Fix output_tokens_details.reasoning_tokens None - [PR #19914](https://github.com/BerriAI/litellm/pull/19914)
+ - Fix stream_chunk_builder to preserve images from streaming chunks - [PR #19654](https://github.com/BerriAI/litellm/pull/19654)
+ - Fix aspectRatio mapping in image edit - [PR #20053](https://github.com/BerriAI/litellm/pull/20053)
+ - Handle unknown models in Azure AI cost calculator - [PR #20150](https://github.com/BerriAI/litellm/pull/20150)
+
+- **[GigaChat](../../docs/providers/gigachat)**
+ - Ensure function content is valid JSON - [PR #19232](https://github.com/BerriAI/litellm/pull/19232)
+
+## LLM API Endpoints
+
+#### Features
+
+- **[Messages API (/messages)](../../docs/mcp)**
+ - Add LiteLLM x Claude Agent SDK Integration - [PR #20035](https://github.com/BerriAI/litellm/pull/20035)
+
+- **[A2A / MCP Gateway API (/a2a, /mcp)](../../docs/mcp)**
+ - Add A2A agent header-based context propagation support - [PR #19504](https://github.com/BerriAI/litellm/pull/19504)
+ - Enable progress notifications for MCP tool calls - [PR #19809](https://github.com/BerriAI/litellm/pull/19809)
+ - Fix support for non-standard MCP URL patterns - [PR #19738](https://github.com/BerriAI/litellm/pull/19738)
+ - Add backward compatibility for legacy A2A card formats (/.well-known/agent.json) - [PR #19949](https://github.com/BerriAI/litellm/pull/19949)
+ - Add support for agent parameter in /interactions endpoint - [PR #19866](https://github.com/BerriAI/litellm/pull/19866)
+
+- **[Responses API (/responses)](../../docs/response_api)**
+ - Fix custom_llm_provider for provider-specific params - [PR #19798](https://github.com/BerriAI/litellm/pull/19798)
+ - Extract input tokens details as dict in ResponseAPILoggingUtils - [PR #20046](https://github.com/BerriAI/litellm/pull/20046)
+
+- **[Batch API (/batches)](../../docs/batches)**
+ - Fix /batches to return encoded ids (from managed objects table) - [PR #19040](https://github.com/BerriAI/litellm/pull/19040)
+ - Fix Batch and File user level permissions - [PR #19981](https://github.com/BerriAI/litellm/pull/19981)
+ - Add cost tracking and usage object in retrieve_batch call type - [PR #19986](https://github.com/BerriAI/litellm/pull/19986)
+
+- **[Embeddings API (/embeddings)](../../docs/embedding/supported_embedding)**
+ - Add supported input formats documentation - [PR #20073](https://github.com/BerriAI/litellm/pull/20073)
+
+- **[RAG API (/rag/ingest, /vector_store)](../../docs/rag_ingest)**
+ - Add UI for /rag/ingest API - Upload docs, pdfs etc to create vector stores - [PR #19822](https://github.com/BerriAI/litellm/pull/19822)
+ - Add support for using S3 Vectors as Vector Store Provider - [PR #19888](https://github.com/BerriAI/litellm/pull/19888)
+ - Add s3_vectors as provider on /vector_store/search API + UI for creating + PDF support - [PR #19895](https://github.com/BerriAI/litellm/pull/19895)
+ - Add permission management for users and teams on Vector Stores - [PR #19972](https://github.com/BerriAI/litellm/pull/19972)
+ - Enable router support for completions in RAG query pipeline - [PR #19550](https://github.com/BerriAI/litellm/pull/19550)
+
+- **[Search API (/search)](../../docs/search)**
+ - Add /list endpoint to list what search tools exist in router - [PR #19969](https://github.com/BerriAI/litellm/pull/19969)
+ - Fix router search tools v2 integration - [PR #19840](https://github.com/BerriAI/litellm/pull/19840)
+
+- **[Passthrough Endpoints (/\{provider\}_passthrough)](../../docs/pass_through/intro)**
+ - Add /openai_passthrough route for OpenAI passthrough requests - [PR #19989](https://github.com/BerriAI/litellm/pull/19989)
+ - Add support for configuring role_mappings via environment variables - [PR #19498](https://github.com/BerriAI/litellm/pull/19498)
+ - Add Vertex AI LLM credentials sensitive keyword "vertex_credentials" for masking - [PR #19551](https://github.com/BerriAI/litellm/pull/19551)
+ - Fix prevention of provider-prefixed model name leaks in responses - [PR #19943](https://github.com/BerriAI/litellm/pull/19943)
+ - Fix proxy support for slashes in Google Vertex generateContent model names - [PR #19737](https://github.com/BerriAI/litellm/pull/19737), [PR #19753](https://github.com/BerriAI/litellm/pull/19753)
+ - Support model names with slashes in Vertex AI passthrough URLs - [PR #19944](https://github.com/BerriAI/litellm/pull/19944)
+ - Fix regression in Vertex AI passthroughs for router models - [PR #19967](https://github.com/BerriAI/litellm/pull/19967)
+ - Add regression tests for Vertex AI passthrough model names - [PR #19855](https://github.com/BerriAI/litellm/pull/19855)
+
+#### Bugs
+
+- **General**
+ - Fix token calculations and refactor - [PR #19696](https://github.com/BerriAI/litellm/pull/19696)
+
+## Management Endpoints / UI
+
+#### Features
+
+- **Proxy CLI Auth**
+ - Add configurable CLI JWT expiration via environment variable - [PR #19780](https://github.com/BerriAI/litellm/pull/19780)
+ - Fix team cli auth flow - [PR #19666](https://github.com/BerriAI/litellm/pull/19666)
+
+- **Virtual Keys**
+ - UI: Auto Truncation of Table Values - [PR #19718](https://github.com/BerriAI/litellm/pull/19718)
+ - Fix Create Key: Expire Key Input Duration - [PR #19807](https://github.com/BerriAI/litellm/pull/19807)
+ - Bulk Update Keys Endpoint - [PR #19886](https://github.com/BerriAI/litellm/pull/19886)
+
+- **Logs View**
+ - **v2 Logs view with side panel and improved UX** - [PR #20091](https://github.com/BerriAI/litellm/pull/20091)
+ - New View to render "Tools" on Logs View - [PR #20093](https://github.com/BerriAI/litellm/pull/20093)
+ - Add Pretty print view of request/response - [PR #20096](https://github.com/BerriAI/litellm/pull/20096)
+ - Add error_message search in Spend Logs Endpoint - [PR #19960](https://github.com/BerriAI/litellm/pull/19960)
+ - UI: Adding Error message search to ui spend logs - [PR #19963](https://github.com/BerriAI/litellm/pull/19963)
+ - Spend Logs: Settings Modal - [PR #19918](https://github.com/BerriAI/litellm/pull/19918)
+ - Fix error_code in Spend Logs metadata - [PR #20015](https://github.com/BerriAI/litellm/pull/20015)
+ - Spend Logs: Show Current Store and Retention Status - [PR #20017](https://github.com/BerriAI/litellm/pull/20017)
+ - Allow Dynamic Setting of store_prompts_in_spend_logs - [PR #19913](https://github.com/BerriAI/litellm/pull/19913)
+ - [Docs: UI Spend Logs Settings](../../docs/proxy/ui_spend_log_settings) - [PR #20197](https://github.com/BerriAI/litellm/pull/20197)
+
+- **Models + Endpoints**
+ - Add sortBy and sortOrder params for /v2/model/info - [PR #19903](https://github.com/BerriAI/litellm/pull/19903)
+ - Fix Sorting for /v2/model/info - [PR #19971](https://github.com/BerriAI/litellm/pull/19971)
+ - UI: Model Page Server Sort - [PR #19908](https://github.com/BerriAI/litellm/pull/19908)
+
+- **Usage & Analytics**
+ - UI: Usage Export: Breakdown by Teams and Keys - [PR #19953](https://github.com/BerriAI/litellm/pull/19953)
+ - UI: Usage: Model Breakdown Per Key - [PR #20039](https://github.com/BerriAI/litellm/pull/20039)
+
+- **UI Improvements**
+ - UI: Allow Admins to control what pages are visible on LeftNav - [PR #19907](https://github.com/BerriAI/litellm/pull/19907)
+ - UI: Add Light/Dark Mode Switch for Development - [PR #19804](https://github.com/BerriAI/litellm/pull/19804)
+ - UI: Dark Mode: Delete Resource Modal - [PR #20098](https://github.com/BerriAI/litellm/pull/20098)
+ - UI: Tables: Reusable Table Sort Component - [PR #19970](https://github.com/BerriAI/litellm/pull/19970)
+ - UI: New Badge Dot Render - [PR #20024](https://github.com/BerriAI/litellm/pull/20024)
+ - UI: Feedback Prompts: Option To Hide Prompts - [PR #19831](https://github.com/BerriAI/litellm/pull/19831)
+ - UI: Navbar: Fixed Default Logo + Bound Logo Box - [PR #20092](https://github.com/BerriAI/litellm/pull/20092)
+ - UI: Navbar: User Dropdown - [PR #20095](https://github.com/BerriAI/litellm/pull/20095)
+ - Change default key type from 'Default' to 'LLM API' - [PR #19516](https://github.com/BerriAI/litellm/pull/19516)
+
+- **Team & User Management**
+ - Fix /team/member_add User Email and ID Verifications - [PR #19814](https://github.com/BerriAI/litellm/pull/19814)
+ - Fix SSO Email Case Sensitivity - [PR #19799](https://github.com/BerriAI/litellm/pull/19799)
+ - UI: Internal User: Bulk Add - [PR #19721](https://github.com/BerriAI/litellm/pull/19721)
+
+- **AI Gateway Features**
+ - Add support for making silent LLM calls without logging - [PR #19544](https://github.com/BerriAI/litellm/pull/19544)
+ - UI: Fix MCP tools instructions to display comma-separated strings - [PR #20101](https://github.com/BerriAI/litellm/pull/20101)
+
+#### Bugs
+
+- Fix Model Name During Fallback - [PR #20177](https://github.com/BerriAI/litellm/pull/20177)
+- Fix Health Endpoints when Callback Objects Defined - [PR #20182](https://github.com/BerriAI/litellm/pull/20182)
+- Fix Unable to reset user max budget to unlimited - [PR #19796](https://github.com/BerriAI/litellm/pull/19796)
+- Fix Password comparison with non-ASCII characters - [PR #19568](https://github.com/BerriAI/litellm/pull/19568)
+- Correct error message for DISABLE_ADMIN_ENDPOINTS - [PR #19861](https://github.com/BerriAI/litellm/pull/19861)
+- Prevent clearing content filter patterns when editing guardrail - [PR #19671](https://github.com/BerriAI/litellm/pull/19671)
+- Fix Prompt Studio history to load tools and system messages - [PR #19920](https://github.com/BerriAI/litellm/pull/19920)
+- Add WATSONX_ZENAPIKEY to WatsonX credentials - [PR #20086](https://github.com/BerriAI/litellm/pull/20086)
+- UI: Vector Store: Allow Config Defined Models to Be Selected - [PR #20031](https://github.com/BerriAI/litellm/pull/20031)
+
+## Logging / Guardrail / Prompt Management Integrations
+
+#### Features
+
+- **[DataDog](../../docs/proxy/logging#datadog)**
+ - Add agent support for LLM Observability - [PR #19574](https://github.com/BerriAI/litellm/pull/19574)
+ - Add datadog cost management support and fix startup callback issue - [PR #19584](https://github.com/BerriAI/litellm/pull/19584)
+ - Add datadog_llm_observability to /health/services allowed list - [PR #19952](https://github.com/BerriAI/litellm/pull/19952)
+ - Check for agent mode before requiring DD_API_KEY/DD_SITE - [PR #20156](https://github.com/BerriAI/litellm/pull/20156)
+
+- **[OpenTelemetry](../../docs/observability/opentelemetry_integration)**
+ - Propagate JWT auth metadata to OTEL spans - [PR #19627](https://github.com/BerriAI/litellm/pull/19627)
+ - Fix thread leak in dynamic header path - [PR #19946](https://github.com/BerriAI/litellm/pull/19946)
+
+- **[Prometheus](../../docs/proxy/logging#prometheus)**
+ - Add callbacks and labels - [PR #19708](https://github.com/BerriAI/litellm/pull/19708)
+ - Add clientip and user agent in metrics - [PR #19717](https://github.com/BerriAI/litellm/pull/19717)
+ - Add tpm-rpm limit metrics - [PR #19725](https://github.com/BerriAI/litellm/pull/19725)
+ - Add model_id label to metrics - [PR #19678](https://github.com/BerriAI/litellm/pull/19678)
+ - Safely handle None metadata in logging - [PR #19691](https://github.com/BerriAI/litellm/pull/19691)
+ - Resolve high CPU when router_settings in DB by avoiding REGISTRY.collect() - [PR #20087](https://github.com/BerriAI/litellm/pull/20087)
+
+- **[Langfuse](../../docs/proxy/logging#langfuse)**
+ - Add litellm_callback_logging_failures_metric for Langfuse, Langfuse Otel and other Otel providers - [PR #19636](https://github.com/BerriAI/litellm/pull/19636)
+
+- **General Logging**
+ - Use return value from CustomLogger.async_post_call_success_hook - [PR #19670](https://github.com/BerriAI/litellm/pull/19670)
+ - Add async_post_call_response_headers_hook to CustomLogger - [PR #20083](https://github.com/BerriAI/litellm/pull/20083)
+ - Add mock client factory pattern and mock support for PostHog, Helicone, and Braintrust integrations - [PR #19707](https://github.com/BerriAI/litellm/pull/19707)
+
+#### Guardrails
+
+- **[Presidio](../../docs/proxy/guardrails/pii_masking_v2)**
+ - Reuse HTTP connections to prevent performance degradation - [PR #19964](https://github.com/BerriAI/litellm/pull/19964)
+
+- **Onyx**
+ - Add timeout to onyx guardrail - [PR #19731](https://github.com/BerriAI/litellm/pull/19731)
+
+- **General**
+ - Add guardrail model argument feature - [PR #19619](https://github.com/BerriAI/litellm/pull/19619)
+ - Fix guardrails issues with streaming-response regex - [PR #19901](https://github.com/BerriAI/litellm/pull/19901)
+ - Remove enterprise requirement for guardrail monitoring (docs) - [PR #19833](https://github.com/BerriAI/litellm/pull/19833)
+
+## Spend Tracking, Budgets and Rate Limiting
+
+- Add event-driven coordination for global spend query to prevent cache stampede - [PR #20030](https://github.com/BerriAI/litellm/pull/20030)
+
+## Performance / Loadbalancing / Reliability improvements
+
+- **Resolve high CPU when router_settings in DB** - by avoiding REGISTRY.collect() in PrometheusServicesLogger - [PR #20087](https://github.com/BerriAI/litellm/pull/20087)
+- **Reuse HTTP connections in Presidio** - to prevent performance degradation - [PR #19964](https://github.com/BerriAI/litellm/pull/19964)
+- **Event-driven coordination for global spend query** - prevent cache stampede - [PR #20030](https://github.com/BerriAI/litellm/pull/20030)
+- Fix recursive Pydantic validation issue - [PR #19531](https://github.com/BerriAI/litellm/pull/19531)
+- Refactor argument handling into helper function to reduce code bloat - [PR #19720](https://github.com/BerriAI/litellm/pull/19720)
+- Optimize logo fetching and resolve MCP import blockers - [PR #19719](https://github.com/BerriAI/litellm/pull/19719)
+- Improve logo download performance using async HTTP client - [PR #20155](https://github.com/BerriAI/litellm/pull/20155)
+- Fix server root path configuration - [PR #19790](https://github.com/BerriAI/litellm/pull/19790)
+- Refactor: Extract transport context creation into separate method - [PR #19794](https://github.com/BerriAI/litellm/pull/19794)
+- Add native_background_mode configuration to override polling_via_cache for specific models - [PR #19899](https://github.com/BerriAI/litellm/pull/19899)
+- Initialize tiktoken environment at import time to enable offline usage - [PR #19882](https://github.com/BerriAI/litellm/pull/19882)
+- Improve tiktoken performance using local cache in lazy loading - [PR #19774](https://github.com/BerriAI/litellm/pull/19774)
+- Fix timeout errors in chat completion calls to be correctly reported in failure callbacks - [PR #19842](https://github.com/BerriAI/litellm/pull/19842)
+- Fix environment variable type handling for NUM_RETRIES - [PR #19507](https://github.com/BerriAI/litellm/pull/19507)
+- Use safe_deep_copy in silent experiment kwargs to prevent mutation - [PR #20170](https://github.com/BerriAI/litellm/pull/20170)
+- Improve error handling by inspecting BadRequestError after all other policy types - [PR #19878](https://github.com/BerriAI/litellm/pull/19878)
+
+## Database Changes
+
+### Schema Updates
+
+| Table | Change Type | Description | PR | Migration |
+| ----- | ----------- | ----------- | -- | --------- |
+| `LiteLLM_ManagedVectorStoresTable` | New Columns | Added `team_id` and `user_id` fields for permission management | [PR #19972](https://github.com/BerriAI/litellm/pull/19972) | [Migration](https://github.com/BerriAI/litellm/blob/main/litellm-proxy-extras/litellm_proxy_extras/migrations/20260131150814_add_team_user_to_vector_stores/migration.sql) |
+
+### Migration Improvements
+
+- Fix Docker: Use correct schema path for Prisma generation - [PR #19631](https://github.com/BerriAI/litellm/pull/19631)
+- Resolve 'relation does not exist' migration errors in setup_database - [PR #19281](https://github.com/BerriAI/litellm/pull/19281)
+- Fix migration issue and improve Docker image stability - [PR #19843](https://github.com/BerriAI/litellm/pull/19843)
+- Run Prisma generate as nobody user in non-root Docker container for security - [PR #20000](https://github.com/BerriAI/litellm/pull/20000)
+- Bump litellm-proxy-extras version to 0.4.28 - [PR #20166](https://github.com/BerriAI/litellm/pull/20166)
+
+## Documentation Updates
+
+- **[Add Claude Agents SDK x LiteLLM Guide](../../docs/mcp)** - [PR #20036](https://github.com/BerriAI/litellm/pull/20036)
+- **[Add Cookbook: Using Claude Agent SDK + MCPs with LiteLLM](https://github.com/BerriAI/litellm/tree/main/cookbook)** - [PR #20081](https://github.com/BerriAI/litellm/pull/20081)
+- Fix A2A Python SDK URL in documentation - [PR #19832](https://github.com/BerriAI/litellm/pull/19832)
+- **[Add Sarvam usage documentation](../../docs/providers/sarvam)** - [PR #19844](https://github.com/BerriAI/litellm/pull/19844)
+- **[Add supported input formats for embeddings](../../docs/embedding/supported_embedding)** - [PR #20073](https://github.com/BerriAI/litellm/pull/20073)
+- **[UI Spend Logs Settings Docs](../../docs/proxy/ui_spend_log_settings)** - [PR #20197](https://github.com/BerriAI/litellm/pull/20197)
+- Add OpenAI Agents SDK to OSS Adopters list in README - [PR #19820](https://github.com/BerriAI/litellm/pull/19820)
+- Update docs: Remove enterprise requirement for guardrail monitoring - [PR #19833](https://github.com/BerriAI/litellm/pull/19833)
+- Add missing environment variable documentation - [PR #20138](https://github.com/BerriAI/litellm/pull/20138)
+- Improve documentation blog index page - [PR #20188](https://github.com/BerriAI/litellm/pull/20188)
+
+## Infrastructure / Testing Improvements
+
+- Add test coverage for Router.get_valid_args and improve code coverage reporting - [PR #19797](https://github.com/BerriAI/litellm/pull/19797)
+- Add validation of model cost map as CI job - [PR #19993](https://github.com/BerriAI/litellm/pull/19993)
+- Add Realtime API benchmarks - [PR #20074](https://github.com/BerriAI/litellm/pull/20074)
+- Add Init Containers support in community helm chart - [PR #19816](https://github.com/BerriAI/litellm/pull/19816)
+- Add libsndfile to main Dockerfile for ARM64 audio processing support - [PR #19776](https://github.com/BerriAI/litellm/pull/19776)
+
+## New Contributors
+
+* @ruanjf made their first contribution in https://github.com/BerriAI/litellm/pull/19551
+* @moh-dev-stack made their first contribution in https://github.com/BerriAI/litellm/pull/19507
+* @formorter made their first contribution in https://github.com/BerriAI/litellm/pull/19498
+* @priyam-that made their first contribution in https://github.com/BerriAI/litellm/pull/19516
+* @marcosgriselli made their first contribution in https://github.com/BerriAI/litellm/pull/19550
+* @natimofeev made their first contribution in https://github.com/BerriAI/litellm/pull/19232
+* @zifeo made their first contribution in https://github.com/BerriAI/litellm/pull/19805
+* @pragyasardana made their first contribution in https://github.com/BerriAI/litellm/pull/19816
+* @ryewilson made their first contribution in https://github.com/BerriAI/litellm/pull/19833
+* @lizhen921 made their first contribution in https://github.com/BerriAI/litellm/pull/19919
+* @boarder7395 made their first contribution in https://github.com/BerriAI/litellm/pull/19666
+* @rushilchugh01 made their first contribution in https://github.com/BerriAI/litellm/pull/19938
+* @cfchase made their first contribution in https://github.com/BerriAI/litellm/pull/19893
+* @ayim made their first contribution in https://github.com/BerriAI/litellm/pull/19872
+* @varunsripad123 made their first contribution in https://github.com/BerriAI/litellm/pull/20018
+* @nht1206 made their first contribution in https://github.com/BerriAI/litellm/pull/20046
+* @genga6 made their first contribution in https://github.com/BerriAI/litellm/pull/20009
+
+**Full Changelog**: https://github.com/BerriAI/litellm/compare/v1.81.3.rc...v1.81.6
diff --git a/docs/my-website/sidebars.js b/docs/my-website/sidebars.js
index ad5019d880a..545d46f7f37 100644
--- a/docs/my-website/sidebars.js
+++ b/docs/my-website/sidebars.js
@@ -42,6 +42,7 @@ const sidebars = {
label: "Guardrails",
items: [
"proxy/guardrails/quick_start",
+ "proxy/guardrails/guardrail_policies",
"proxy/guardrails/guardrail_load_balancing",
{
type: "category",
@@ -78,6 +79,7 @@ const sidebars = {
"proxy/guardrails/panw_prisma_airs",
"proxy/guardrails/secret_detection",
"proxy/guardrails/custom_guardrail",
+ "proxy/guardrails/custom_code_guardrail",
"proxy/guardrails/prompt_injection",
"proxy/guardrails/tool_permission",
"proxy/guardrails/zscaler_ai_guard",
@@ -127,8 +129,10 @@ const sidebars = {
"tutorials/claude_mcp",
"tutorials/claude_non_anthropic_models",
"tutorials/claude_code_plugin_marketplace",
+ "tutorials/claude_code_beta_headers",
]
},
+ "tutorials/opencode_integration",
"tutorials/cost_tracking_coding",
"tutorials/cursor_integration",
"tutorials/github_copilot_integration",
@@ -137,6 +141,22 @@ const sidebars = {
"tutorials/openai_codex"
]
},
+ {
+ type: "category",
+ label: "Agent SDKs",
+ link: {
+ type: "generated-index",
+ title: "Agent SDKs",
+ description: "Use LiteLLM with agent frameworks and SDKs",
+ slug: "/agent_sdks"
+ },
+ items: [
+ "tutorials/claude_agent_sdk",
+ "tutorials/copilotkit_sdk",
+ "tutorials/google_adk",
+ "tutorials/livekit_xai_realtime",
+ ]
+ },
],
// But you can create a sidebar manually
@@ -272,11 +292,19 @@ const sidebars = {
"proxy/custom_sso",
"proxy/ai_hub",
"proxy/model_compare_ui",
- "proxy/public_teams",
- "proxy/self_serve",
- "proxy/ui/bulk_edit_users",
"proxy/ui_credentials",
"tutorials/scim_litellm",
+ {
+ type: "category",
+ label: "UI User/Team Management",
+ items: [
+ "proxy/access_control",
+ "proxy/public_teams",
+ "proxy/self_serve",
+ "proxy/ui/bulk_edit_users",
+ "proxy/ui/page_visibility",
+ ]
+ },
{
type: "category",
label: "UI Usage Tracking",
@@ -290,6 +318,7 @@ const sidebars = {
label: "UI Logs",
items: [
"proxy/ui_logs",
+ "proxy/ui_spend_log_settings",
"proxy/ui_logs_sessions",
"proxy/deleted_keys_teams"
]
@@ -362,6 +391,7 @@ const sidebars = {
label: "Load Balancing, Routing, Fallbacks",
href: "https://docs.litellm.ai/docs/routing-load-balancing",
},
+ "traffic_mirroring",
{
type: "category",
label: "Logging, Alerting, Metrics",
@@ -416,6 +446,7 @@ const sidebars = {
label: "Spend Tracking",
items: [
"proxy/cost_tracking",
+ "proxy/request_tags",
"proxy/custom_pricing",
"proxy/pricing_calculator",
"proxy/provider_margins",
@@ -442,6 +473,7 @@ const sidebars = {
label: "/a2a - A2A Agent Gateway",
items: [
"a2a",
+ "a2a_invoking_agents",
"a2a_cost_tracking",
"a2a_agent_permissions"
],
@@ -511,6 +543,8 @@ const sidebars = {
items: [
"mcp",
"mcp_usage",
+ "mcp_public_internet",
+ "mcp_semantic_filter",
"mcp_control",
"mcp_cost",
"mcp_guardrail",
@@ -689,6 +723,7 @@ const sidebars = {
"providers/bedrock_agents",
"providers/bedrock_writer",
"providers/bedrock_batches",
+ "providers/bedrock_realtime_with_audio",
"providers/aws_polly",
"providers/bedrock_vector_store",
]
@@ -773,6 +808,7 @@ const sidebars = {
"providers/oci",
"providers/ollama",
"providers/openrouter",
+ "providers/sarvam",
"providers/ovhcloud",
"providers/perplexity",
"providers/petals",
@@ -820,7 +856,14 @@ const sidebars = {
"providers/watsonx/audio_transcription",
]
},
- "providers/xai",
+ {
+ type: "category",
+ label: "xAI",
+ items: [
+ "providers/xai",
+ "providers/xai_realtime",
+ ]
+ },
"providers/xiaomi_mimo",
"providers/xinference",
"providers/zai",
@@ -841,6 +884,7 @@ const sidebars = {
"completion/image_generation_chat",
"completion/json_mode",
"completion/knowledgebase",
+ "providers/anthropic_tool_search",
"guides/code_interpreter",
"completion/message_trimming",
"completion/model_alias",
@@ -877,6 +921,7 @@ const sidebars = {
"scheduler",
"proxy/auto_routing",
"proxy/load_balancing",
+ "proxy/keys_teams_router_settings",
"proxy/provider_budget_routing",
"proxy/reliability",
"proxy/fallback_management",
@@ -917,7 +962,6 @@ const sidebars = {
type: "category",
label: "LiteLLM Python SDK Tutorials",
items: [
- 'tutorials/google_adk',
'tutorials/azure_openai',
'tutorials/instructor',
"tutorials/gradio_integration",
@@ -1013,8 +1057,10 @@ const sidebars = {
type: "category",
label: "Issue Reporting",
items: [
+ "troubleshoot/prisma_migrations",
"troubleshoot/cpu_issues",
"troubleshoot/memory_issues",
+ "troubleshoot/spend_queue_warnings",
],
},
],
diff --git a/docs/my-website/src/theme/BlogListPage/index.js b/docs/my-website/src/theme/BlogListPage/index.js
new file mode 100644
index 00000000000..277556a3528
--- /dev/null
+++ b/docs/my-website/src/theme/BlogListPage/index.js
@@ -0,0 +1,123 @@
+import React from 'react';
+import Layout from '@theme/Layout';
+import Link from '@docusaurus/Link';
+import styles from './styles.module.css';
+
+const TAG_COLORS = {
+ gemini: {bg: '#d2e3fc', text: '#174ea6', darkBg: '#1a3a5c', darkText: '#8ab4f8'},
+ anthropic: {bg: '#fde0c4', text: '#b33d00', darkBg: '#4a2800', darkText: '#ffb74d'},
+ claude: {bg: '#fde0c4', text: '#b33d00', darkBg: '#4a2800', darkText: '#ffb74d'},
+ llms: {bg: '#c8e6c9', text: '#1b5e20', darkBg: '#1b3d1f', darkText: '#81c784'},
+};
+
+function hashHue(str) {
+ let hash = 0;
+ for (let i = 0; i < str.length; i++) {
+ hash = str.charCodeAt(i) + ((hash << 5) - hash);
+ }
+ return Math.abs(hash) % 360;
+}
+
+function getTagColor(label) {
+ const key = label.toLowerCase();
+ for (const [k, v] of Object.entries(TAG_COLORS)) {
+ if (key === k) return v;
+ }
+ const hue = hashHue(key);
+ return {
+ bg: `hsl(${hue}, 40%, 90%)`,
+ text: `hsl(${hue}, 60%, 25%)`,
+ darkBg: `hsl(${hue}, 40%, 20%)`,
+ darkText: `hsl(${hue}, 50%, 75%)`,
+ };
+}
+
+function formatDate(dateStr) {
+ const d = new Date(dateStr);
+ const now = new Date();
+ const diffDays = Math.floor((now - d) / (1000 * 60 * 60 * 24));
+ if (diffDays <= 0) return 'Today';
+ if (diffDays === 1) return '1d ago';
+ if (diffDays < 30) return `${diffDays}d ago`;
+ return d.toLocaleDateString('en-US', {month: 'short', day: 'numeric', year: 'numeric'});
+}
+
+function BlogCard({post, featured}) {
+ const {title, permalink, date, description, tags} = post;
+ const visibleTags = (tags || []).slice(0, 3);
+
+ return (
+
+
+
+ ⚠️ Note: Your API requests will continue to work, but you should monitor your usage closely.
+ If you reach your maximum budget, requests will be rejected.
+
+
+ You can view your usage and manage your budget in the LiteLLM Dashboard.
+
+ If you have any questions, please send an email to {email_support_contact}
+
+ Best,
+ The LiteLLM team
+"""
+
MAX_BUDGET_ALERT_EMAIL_TEMPLATE = """
diff --git a/litellm/integrations/gcs_bucket/gcs_bucket_base.py b/litellm/integrations/gcs_bucket/gcs_bucket_base.py
index 2612face050..b1db9ec9588 100644
--- a/litellm/integrations/gcs_bucket/gcs_bucket_base.py
+++ b/litellm/integrations/gcs_bucket/gcs_bucket_base.py
@@ -2,6 +2,13 @@ import json
import os
from typing import TYPE_CHECKING, Any, Dict, Optional, Tuple, Union
+from litellm.integrations.gcs_bucket.gcs_bucket_mock_client import (
+ should_use_gcs_mock,
+ create_mock_gcs_client,
+ mock_vertex_auth_methods,
+)
+
+
from litellm._logging import verbose_logger
from litellm.integrations.custom_batch_logger import CustomBatchLogger
from litellm.llms.custom_httpx.http_handler import (
@@ -20,6 +27,12 @@ IAM_AUTH_KEY = "IAM_AUTH"
class GCSBucketBase(CustomBatchLogger):
def __init__(self, bucket_name: Optional[str] = None, **kwargs) -> None:
+ self.is_mock_mode = should_use_gcs_mock()
+
+ if self.is_mock_mode:
+ mock_vertex_auth_methods()
+ create_mock_gcs_client()
+
self.async_httpx_client = get_async_httpx_client(
llm_provider=httpxSpecialProvider.LoggingCallback
)
diff --git a/litellm/integrations/gcs_bucket/gcs_bucket_mock_client.py b/litellm/integrations/gcs_bucket/gcs_bucket_mock_client.py
new file mode 100644
index 00000000000..2d14f5eb962
--- /dev/null
+++ b/litellm/integrations/gcs_bucket/gcs_bucket_mock_client.py
@@ -0,0 +1,192 @@
+"""
+Mock client for GCS Bucket integration testing.
+
+This module intercepts GCS API calls and Vertex AI auth calls, returning successful
+mock responses, allowing full code execution without making actual network calls.
+
+Usage:
+ Set GCS_MOCK=true in environment variables or config to enable mock mode.
+"""
+
+import asyncio
+
+from litellm._logging import verbose_logger
+from litellm.integrations.mock_client_factory import MockClientConfig, create_mock_client_factory, MockResponse
+
+# Use factory for POST handler
+_config = MockClientConfig(
+ name="GCS",
+ env_var="GCS_MOCK",
+ default_latency_ms=150,
+ default_status_code=200,
+ default_json_data={"kind": "storage#object", "name": "mock-object"},
+ url_matchers=["storage.googleapis.com"],
+ patch_async_handler=True,
+ patch_sync_client=False,
+)
+
+_create_mock_gcs_post, should_use_gcs_mock = create_mock_client_factory(_config)
+
+# Store original methods for GET/DELETE (GCS-specific)
+_original_async_handler_get = None
+_original_async_handler_delete = None
+_mocks_initialized = False
+
+# Default mock latency in seconds (simulates network round-trip)
+# Typical GCS API calls take 100-300ms for uploads, 50-150ms for GET/DELETE
+_MOCK_LATENCY_SECONDS = float(__import__("os").getenv("GCS_MOCK_LATENCY_MS", "150")) / 1000.0
+
+
+async def _mock_async_handler_get(self, url, params=None, headers=None, follow_redirects=None):
+ """Monkey-patched AsyncHTTPHandler.get that intercepts GCS calls."""
+ # Only mock GCS API calls
+ if isinstance(url, str) and "storage.googleapis.com" in url:
+ verbose_logger.info(f"[GCS MOCK] GET to {url}")
+ await asyncio.sleep(_MOCK_LATENCY_SECONDS)
+ # Return a minimal but valid StandardLoggingPayload JSON string as bytes
+ # This matches what GCS returns when downloading with ?alt=media
+ mock_payload = {
+ "id": "mock-request-id",
+ "trace_id": "mock-trace-id",
+ "call_type": "completion",
+ "stream": False,
+ "response_cost": 0.0,
+ "status": "success",
+ "status_fields": {"llm_api_status": "success"},
+ "custom_llm_provider": "mock",
+ "total_tokens": 0,
+ "prompt_tokens": 0,
+ "completion_tokens": 0,
+ "startTime": 0.0,
+ "endTime": 0.0,
+ "completionStartTime": 0.0,
+ "response_time": 0.0,
+ "model_map_information": {"model": "mock-model"},
+ "model": "mock-model",
+ "model_id": None,
+ "model_group": None,
+ "api_base": "https://api.mock.com",
+ "metadata": {},
+ "cache_hit": None,
+ "cache_key": None,
+ "saved_cache_cost": 0.0,
+ "request_tags": [],
+ "end_user": None,
+ "requester_ip_address": None,
+ "messages": None,
+ "response": None,
+ "error_str": None,
+ "error_information": None,
+ "model_parameters": {},
+ "hidden_params": {},
+ "guardrail_information": None,
+ "standard_built_in_tools_params": None,
+ }
+ return MockResponse(
+ status_code=200,
+ json_data=mock_payload,
+ url=url,
+ elapsed_seconds=_MOCK_LATENCY_SECONDS
+ )
+ if _original_async_handler_get is not None:
+ return await _original_async_handler_get(self, url=url, params=params, headers=headers, follow_redirects=follow_redirects)
+ raise RuntimeError("Original AsyncHTTPHandler.get not available")
+
+
+async def _mock_async_handler_delete(self, url, data=None, json=None, params=None, headers=None, timeout=None, stream=False, content=None):
+ """Monkey-patched AsyncHTTPHandler.delete that intercepts GCS calls."""
+ # Only mock GCS API calls
+ if isinstance(url, str) and "storage.googleapis.com" in url:
+ verbose_logger.info(f"[GCS MOCK] DELETE to {url}")
+ await asyncio.sleep(_MOCK_LATENCY_SECONDS)
+ # DELETE returns 204 No Content with empty body (not JSON)
+ return MockResponse(
+ status_code=204,
+ json_data=None, # Empty body for DELETE
+ url=url,
+ elapsed_seconds=_MOCK_LATENCY_SECONDS
+ )
+ if _original_async_handler_delete is not None:
+ return await _original_async_handler_delete(self, url=url, data=data, json=json, params=params, headers=headers, timeout=timeout, stream=stream, content=content)
+ raise RuntimeError("Original AsyncHTTPHandler.delete not available")
+
+
+def create_mock_gcs_client():
+ """
+ Monkey-patch AsyncHTTPHandler methods to intercept GCS calls.
+
+ AsyncHTTPHandler is used by LiteLLM's get_async_httpx_client() which is what
+ GCSBucketBase uses for making API calls.
+
+ This function is idempotent - it only initializes mocks once, even if called multiple times.
+ """
+ global _original_async_handler_get, _original_async_handler_delete, _mocks_initialized
+
+ # Use factory for POST handler
+ _create_mock_gcs_post()
+
+ # If already initialized, skip GET/DELETE patching
+ if _mocks_initialized:
+ return
+
+ verbose_logger.debug("[GCS MOCK] Initializing GCS GET/DELETE handlers...")
+
+ # Patch GET and DELETE handlers (GCS-specific)
+ from litellm.llms.custom_httpx.http_handler import AsyncHTTPHandler
+
+ if _original_async_handler_get is None:
+ _original_async_handler_get = AsyncHTTPHandler.get
+ AsyncHTTPHandler.get = _mock_async_handler_get # type: ignore
+ verbose_logger.debug("[GCS MOCK] Patched AsyncHTTPHandler.get")
+
+ if _original_async_handler_delete is None:
+ _original_async_handler_delete = AsyncHTTPHandler.delete
+ AsyncHTTPHandler.delete = _mock_async_handler_delete # type: ignore
+ verbose_logger.debug("[GCS MOCK] Patched AsyncHTTPHandler.delete")
+
+ verbose_logger.debug(f"[GCS MOCK] Mock latency set to {_MOCK_LATENCY_SECONDS*1000:.0f}ms")
+ verbose_logger.debug("[GCS MOCK] GCS mock client initialization complete")
+
+ _mocks_initialized = True
+
+
+def mock_vertex_auth_methods():
+ """
+ Monkey-patch Vertex AI auth methods to return fake tokens.
+ This prevents auth failures when GCS_MOCK is enabled.
+
+ This function is idempotent - it only patches once, even if called multiple times.
+ """
+ from litellm.llms.vertex_ai.vertex_llm_base import VertexBase
+
+ # Store original methods if not already stored
+ if not hasattr(VertexBase, '_original_ensure_access_token_async'):
+ setattr(VertexBase, '_original_ensure_access_token_async', VertexBase._ensure_access_token_async)
+ setattr(VertexBase, '_original_ensure_access_token', VertexBase._ensure_access_token)
+ setattr(VertexBase, '_original_get_token_and_url', VertexBase._get_token_and_url)
+
+ async def _mock_ensure_access_token_async(self, credentials, project_id, custom_llm_provider):
+ """Mock async auth method - returns fake token."""
+ verbose_logger.debug("[GCS MOCK] Vertex AI auth: _ensure_access_token_async called")
+ return ("mock-gcs-token", "mock-project-id")
+
+ def _mock_ensure_access_token(self, credentials, project_id, custom_llm_provider):
+ """Mock sync auth method - returns fake token."""
+ verbose_logger.debug("[GCS MOCK] Vertex AI auth: _ensure_access_token called")
+ return ("mock-gcs-token", "mock-project-id")
+
+ def _mock_get_token_and_url(self, model, auth_header, vertex_credentials, vertex_project,
+ vertex_location, gemini_api_key, stream, custom_llm_provider, api_base):
+ """Mock get_token_and_url - returns fake token."""
+ verbose_logger.debug("[GCS MOCK] Vertex AI auth: _get_token_and_url called")
+ return ("mock-gcs-token", "https://storage.googleapis.com")
+
+ # Patch the methods
+ VertexBase._ensure_access_token_async = _mock_ensure_access_token_async # type: ignore
+ VertexBase._ensure_access_token = _mock_ensure_access_token # type: ignore
+ VertexBase._get_token_and_url = _mock_get_token_and_url # type: ignore
+
+ verbose_logger.debug("[GCS MOCK] Patched Vertex AI auth methods")
+
+
+# should_use_gcs_mock is already created by the factory
diff --git a/litellm/integrations/helicone.py b/litellm/integrations/helicone.py
index 198cbaf4058..b996813b4e7 100644
--- a/litellm/integrations/helicone.py
+++ b/litellm/integrations/helicone.py
@@ -4,6 +4,11 @@ import os
import traceback
import litellm
+from litellm._logging import verbose_logger
+from litellm.integrations.helicone_mock_client import (
+ should_use_helicone_mock,
+ create_mock_helicone_client,
+)
class HeliconeLogger:
@@ -22,6 +27,11 @@ class HeliconeLogger:
def __init__(self):
# Instance variables
+ self.is_mock_mode = should_use_helicone_mock()
+ if self.is_mock_mode:
+ create_mock_helicone_client()
+ verbose_logger.info("[HELICONE MOCK] Helicone logger initialized in mock mode")
+
self.provider_url = "https://api.openai.com/v1"
self.key = os.getenv("HELICONE_API_KEY")
self.api_base = os.getenv("HELICONE_API_BASE") or "https://api.hconeai.com"
@@ -185,7 +195,10 @@ class HeliconeLogger:
}
response = litellm.module_level_client.post(url, headers=headers, json=data)
if response.status_code == 200:
- print_verbose("Helicone Logging - Success!")
+ if self.is_mock_mode:
+ print_verbose("[HELICONE MOCK] Helicone Logging - Successfully mocked!")
+ else:
+ print_verbose("Helicone Logging - Success!")
else:
print_verbose(
f"Helicone Logging - Error Request was not successful. Status Code: {response.status_code}"
diff --git a/litellm/integrations/helicone_mock_client.py b/litellm/integrations/helicone_mock_client.py
new file mode 100644
index 00000000000..0f4670a1d2c
--- /dev/null
+++ b/litellm/integrations/helicone_mock_client.py
@@ -0,0 +1,32 @@
+"""
+Mock HTTP client for Helicone integration testing.
+
+This module intercepts Helicone API calls and returns successful mock responses,
+allowing full code execution without making actual network calls.
+
+Usage:
+ Set HELICONE_MOCK=true in environment variables or config to enable mock mode.
+"""
+
+from litellm.integrations.mock_client_factory import MockClientConfig, create_mock_client_factory
+
+# Create mock client using factory
+# Helicone uses HTTPHandler which internally uses httpx.Client.send(), not httpx.Client.post()
+_config = MockClientConfig(
+ name="HELICONE",
+ env_var="HELICONE_MOCK",
+ default_latency_ms=100,
+ default_status_code=200,
+ default_json_data={"status": "success"},
+ url_matchers=[
+ ".hconeai.com",
+ "hconeai.com",
+ ".helicone.ai",
+ "helicone.ai",
+ ],
+ patch_async_handler=False,
+ patch_sync_client=False, # HTTPHandler uses self.client.send(), not self.client.post()
+ patch_http_handler=True, # Patch HTTPHandler.post directly
+)
+
+create_mock_helicone_client, should_use_helicone_mock = create_mock_client_factory(_config)
diff --git a/litellm/integrations/langfuse/langfuse.py b/litellm/integrations/langfuse/langfuse.py
index 8087c17cafe..7bf97665fd2 100644
--- a/litellm/integrations/langfuse/langfuse.py
+++ b/litellm/integrations/langfuse/langfuse.py
@@ -23,8 +23,13 @@ from litellm.constants import MAX_LANGFUSE_INITIALIZED_CLIENTS
from litellm.litellm_core_utils.core_helpers import (
safe_deep_copy,
reconstruct_model_name,
+ filter_exceptions_from_params,
)
from litellm.litellm_core_utils.redact_messages import redact_user_api_key_info
+from litellm.integrations.langfuse.langfuse_mock_client import (
+ create_mock_langfuse_client,
+ should_use_langfuse_mock,
+)
from litellm.llms.custom_httpx.http_handler import _get_httpx_client
from litellm.secret_managers.main import str_to_bool
from litellm.types.integrations.langfuse import *
@@ -71,9 +76,8 @@ def _extract_cache_read_input_tokens(usage_obj) -> int:
# Check prompt_tokens_details.cached_tokens (used by Gemini and other providers)
if hasattr(usage_obj, "prompt_tokens_details"):
prompt_tokens_details = getattr(usage_obj, "prompt_tokens_details", None)
- if (
- prompt_tokens_details is not None
- and hasattr(prompt_tokens_details, "cached_tokens")
+ if prompt_tokens_details is not None and hasattr(
+ prompt_tokens_details, "cached_tokens"
):
cached_tokens = getattr(prompt_tokens_details, "cached_tokens", None)
if (
@@ -119,8 +123,14 @@ class LangFuseLogger:
self.langfuse_flush_interval = LangFuseLogger._get_langfuse_flush_interval(
flush_interval
)
- http_client = _get_httpx_client()
- self.langfuse_client = http_client.client
+
+ if should_use_langfuse_mock():
+ self.langfuse_client = create_mock_langfuse_client()
+ self.is_mock_mode = True
+ else:
+ http_client = _get_httpx_client()
+ self.langfuse_client = http_client.client
+ self.is_mock_mode = False
parameters = {
"public_key": self.public_key,
@@ -139,11 +149,15 @@ class LangFuseLogger:
# set the current langfuse project id in the environ
# this is used by Alerting to link to the correct project
- try:
- project_id = self.Langfuse.client.projects.get().data[0].id
- os.environ["LANGFUSE_PROJECT_ID"] = project_id
- except Exception:
- project_id = None
+ if self.is_mock_mode:
+ os.environ["LANGFUSE_PROJECT_ID"] = "mock-project-id"
+ verbose_logger.debug("Langfuse Mock: Using mock project ID")
+ else:
+ try:
+ project_id = self.Langfuse.client.projects.get().data[0].id
+ os.environ["LANGFUSE_PROJECT_ID"] = project_id
+ except Exception:
+ project_id = None
if os.getenv("UPSTREAM_LANGFUSE_SECRET_KEY") is not None:
upstream_langfuse_debug = (
@@ -526,7 +540,6 @@ class LangFuseLogger:
verbose_logger.debug("Langfuse Layer Logging - logging to langfuse v2")
try:
- metadata = metadata or {}
standard_logging_object: Optional[StandardLoggingPayload] = cast(
Optional[StandardLoggingPayload],
kwargs.get("standard_logging_object", None),
@@ -692,9 +705,10 @@ class LangFuseLogger:
clean_metadata["litellm_response_cost"] = cost
if standard_logging_object is not None:
- clean_metadata["hidden_params"] = standard_logging_object[
- "hidden_params"
- ]
+ hidden_params = standard_logging_object.get("hidden_params", {})
+ clean_metadata["hidden_params"] = filter_exceptions_from_params(
+ hidden_params
+ )
if (
litellm.langfuse_default_tags is not None
diff --git a/litellm/integrations/langfuse/langfuse_mock_client.py b/litellm/integrations/langfuse/langfuse_mock_client.py
new file mode 100644
index 00000000000..8ed6cff8d47
--- /dev/null
+++ b/litellm/integrations/langfuse/langfuse_mock_client.py
@@ -0,0 +1,35 @@
+"""
+Mock httpx client for Langfuse integration testing.
+
+This module intercepts Langfuse API calls and returns successful mock responses,
+allowing full code execution without making actual network calls.
+
+Usage:
+ Set LANGFUSE_MOCK=true in environment variables or config to enable mock mode.
+"""
+
+import httpx
+from litellm.integrations.mock_client_factory import MockClientConfig, create_mock_client_factory
+
+# Create mock client using factory
+_config = MockClientConfig(
+ name="LANGFUSE",
+ env_var="LANGFUSE_MOCK",
+ default_latency_ms=100,
+ default_status_code=200,
+ default_json_data={"status": "success"},
+ url_matchers=[
+ ".langfuse.com",
+ "langfuse.com",
+ ],
+ patch_async_handler=False,
+ patch_sync_client=True,
+)
+
+_create_mock_langfuse_client_internal, should_use_langfuse_mock = create_mock_client_factory(_config)
+
+# Langfuse needs to return an httpx.Client instance
+def create_mock_langfuse_client():
+ """Create and return an httpx.Client instance - the monkey-patch intercepts all calls."""
+ _create_mock_langfuse_client_internal()
+ return httpx.Client()
diff --git a/litellm/integrations/langfuse/langfuse_otel.py b/litellm/integrations/langfuse/langfuse_otel.py
index 08493a0e8ec..8955d3619f7 100644
--- a/litellm/integrations/langfuse/langfuse_otel.py
+++ b/litellm/integrations/langfuse/langfuse_otel.py
@@ -8,9 +8,8 @@ from litellm.integrations.arize import _utils
from litellm.integrations.langfuse.langfuse_otel_attributes import (
LangfuseLLMObsOTELAttributes,
)
-from litellm.integrations.opentelemetry import OpenTelemetry
+from litellm.integrations.opentelemetry import OpenTelemetry, OpenTelemetryConfig
from litellm.types.integrations.langfuse_otel import (
- LangfuseOtelConfig,
LangfuseSpanAttributes,
)
from litellm.types.utils import StandardCallbackDynamicParams
@@ -18,17 +17,8 @@ from litellm.types.utils import StandardCallbackDynamicParams
if TYPE_CHECKING:
from opentelemetry.trace import Span as _Span
- from litellm.integrations.opentelemetry import (
- OpenTelemetryConfig as _OpenTelemetryConfig,
- )
- from litellm.types.integrations.arize import Protocol as _Protocol
-
- Protocol = _Protocol
- OpenTelemetryConfig = _OpenTelemetryConfig
Span = Union[_Span, Any]
else:
- Protocol = Any
- OpenTelemetryConfig = Any
Span = Any
@@ -37,8 +27,12 @@ LANGFUSE_CLOUD_US_ENDPOINT = "https://us.cloud.langfuse.com/api/public/otel"
class LangfuseOtelLogger(OpenTelemetry):
- def __init__(self, *args, **kwargs):
- super().__init__(*args, **kwargs)
+ def __init__(self, config=None, *args, **kwargs):
+ # Prevent LangfuseOtelLogger from modifying global environment variables by constructing config manually
+ # and passing it to the parent OpenTelemetry class
+ if config is None:
+ config = self._create_open_telemetry_config_from_langfuse_env()
+ super().__init__(config=config, *args, **kwargs)
@staticmethod
def set_langfuse_otel_attributes(span: Span, kwargs, response_obj):
@@ -114,6 +108,10 @@ class LangfuseOtelLogger(OpenTelemetry):
for key, enum_attr in mapping.items():
if key in metadata and metadata[key] is not None:
value = metadata[key]
+ if key == "trace_id" and isinstance(value, str):
+ # trace_id must be 32 hex char no dashes for langfuse : Litellm sends uuid with dashes (might be breaking at some point)
+ value = value.replace("-", "")
+
if isinstance(value, (list, dict)):
try:
value = json.dumps(value)
@@ -265,8 +263,47 @@ class LangfuseOtelLogger(OpenTelemetry):
"""
return os.environ.get("LANGFUSE_OTEL_HOST") or os.environ.get("LANGFUSE_HOST")
+ def _create_open_telemetry_config_from_langfuse_env(self) -> OpenTelemetryConfig:
+ """
+ Creates OpenTelemetryConfig from Langfuse environment variables.
+ Does NOT modify global environment variables.
+ """
+ from litellm.integrations.opentelemetry import OpenTelemetryConfig
+
+ public_key = os.environ.get("LANGFUSE_PUBLIC_KEY", None)
+ secret_key = os.environ.get("LANGFUSE_SECRET_KEY", None)
+
+ if not public_key or not secret_key:
+ # If no keys, return default from env (likely logging to console or something else)
+ return OpenTelemetryConfig.from_env()
+
+ # Determine endpoint - default to US cloud
+ langfuse_host = LangfuseOtelLogger._get_langfuse_otel_host()
+
+ if langfuse_host:
+ # If LANGFUSE_HOST is provided, construct OTEL endpoint from it
+ if not langfuse_host.startswith("http"):
+ langfuse_host = "https://" + langfuse_host
+ endpoint = f"{langfuse_host.rstrip('/')}/api/public/otel"
+ verbose_logger.debug(f"Using Langfuse OTEL endpoint from host: {endpoint}")
+ else:
+ # Default to US cloud endpoint
+ endpoint = LANGFUSE_CLOUD_US_ENDPOINT
+ verbose_logger.debug(f"Using Langfuse US cloud endpoint: {endpoint}")
+
+ auth_header = LangfuseOtelLogger._get_langfuse_authorization_header(
+ public_key=public_key, secret_key=secret_key
+ )
+ otlp_auth_headers = f"Authorization={auth_header}"
+
+ return OpenTelemetryConfig(
+ exporter="otlp_http",
+ endpoint=endpoint,
+ headers=otlp_auth_headers,
+ )
+
@staticmethod
- def get_langfuse_otel_config() -> LangfuseOtelConfig:
+ def get_langfuse_otel_config() -> "OpenTelemetryConfig":
"""
Retrieves the Langfuse OpenTelemetry configuration based on environment variables.
@@ -276,7 +313,7 @@ class LangfuseOtelLogger(OpenTelemetry):
LANGFUSE_HOST: Optional. Custom Langfuse host URL. Defaults to US cloud.
Returns:
- LangfuseOtelConfig: A Pydantic model containing Langfuse OTEL configuration.
+ OpenTelemetryConfig: A Pydantic model containing Langfuse OTEL configuration.
Raises:
ValueError: If required keys are missing.
@@ -308,12 +345,14 @@ class LangfuseOtelLogger(OpenTelemetry):
)
otlp_auth_headers = f"Authorization={auth_header}"
- # Set standard OTEL environment variables
- os.environ["OTEL_EXPORTER_OTLP_ENDPOINT"] = endpoint
- os.environ["OTEL_EXPORTER_OTLP_HEADERS"] = otlp_auth_headers
+ # Prevent modification of global env vars which causes leakage
+ # os.environ["OTEL_EXPORTER_OTLP_ENDPOINT"] = endpoint
+ # os.environ["OTEL_EXPORTER_OTLP_HEADERS"] = otlp_auth_headers
- return LangfuseOtelConfig(
- otlp_auth_headers=otlp_auth_headers, protocol="otlp_http"
+ return OpenTelemetryConfig(
+ exporter="otlp_http",
+ endpoint=endpoint,
+ headers=otlp_auth_headers,
)
@staticmethod
diff --git a/litellm/integrations/langfuse/langfuse_prompt_management.py b/litellm/integrations/langfuse/langfuse_prompt_management.py
index 8f73eabad44..3986fc6a6ef 100644
--- a/litellm/integrations/langfuse/langfuse_prompt_management.py
+++ b/litellm/integrations/langfuse/langfuse_prompt_management.py
@@ -300,43 +300,59 @@ class LangfusePromptManagement(LangFuseLogger, PromptManagementBase, CustomLogge
)
async def async_log_success_event(self, kwargs, response_obj, start_time, end_time):
- standard_callback_dynamic_params = kwargs.get(
- "standard_callback_dynamic_params"
- )
- langfuse_logger_to_use = LangFuseHandler.get_langfuse_logger_for_request(
- globalLangfuseLogger=self,
- standard_callback_dynamic_params=standard_callback_dynamic_params,
- in_memory_dynamic_logger_cache=in_memory_dynamic_logger_cache,
- )
- langfuse_logger_to_use.log_event_on_langfuse(
- kwargs=kwargs,
- response_obj=response_obj,
- start_time=start_time,
- end_time=end_time,
- user_id=kwargs.get("user", None),
- )
+ try:
+ standard_callback_dynamic_params = kwargs.get(
+ "standard_callback_dynamic_params"
+ )
+ langfuse_logger_to_use = LangFuseHandler.get_langfuse_logger_for_request(
+ globalLangfuseLogger=self,
+ standard_callback_dynamic_params=standard_callback_dynamic_params,
+ in_memory_dynamic_logger_cache=in_memory_dynamic_logger_cache,
+ )
+ langfuse_logger_to_use.log_event_on_langfuse(
+ kwargs=kwargs,
+ response_obj=response_obj,
+ start_time=start_time,
+ end_time=end_time,
+ user_id=kwargs.get("user", None),
+ )
+ except Exception as e:
+ from litellm._logging import verbose_logger
+
+ verbose_logger.exception(
+ f"Langfuse Layer Error - Exception occurred while logging success event: {str(e)}"
+ )
+ self.handle_callback_failure(callback_name="langfuse")
async def async_log_failure_event(self, kwargs, response_obj, start_time, end_time):
- standard_callback_dynamic_params = kwargs.get(
- "standard_callback_dynamic_params"
- )
- langfuse_logger_to_use = LangFuseHandler.get_langfuse_logger_for_request(
- globalLangfuseLogger=self,
- standard_callback_dynamic_params=standard_callback_dynamic_params,
- in_memory_dynamic_logger_cache=in_memory_dynamic_logger_cache,
- )
- standard_logging_object = cast(
- Optional[StandardLoggingPayload],
- kwargs.get("standard_logging_object", None),
- )
- if standard_logging_object is None:
- return
- langfuse_logger_to_use.log_event_on_langfuse(
- start_time=start_time,
- end_time=end_time,
- response_obj=None,
- user_id=kwargs.get("user", None),
- status_message=standard_logging_object["error_str"],
- level="ERROR",
- kwargs=kwargs,
- )
+ try:
+ standard_callback_dynamic_params = kwargs.get(
+ "standard_callback_dynamic_params"
+ )
+ langfuse_logger_to_use = LangFuseHandler.get_langfuse_logger_for_request(
+ globalLangfuseLogger=self,
+ standard_callback_dynamic_params=standard_callback_dynamic_params,
+ in_memory_dynamic_logger_cache=in_memory_dynamic_logger_cache,
+ )
+ standard_logging_object = cast(
+ Optional[StandardLoggingPayload],
+ kwargs.get("standard_logging_object", None),
+ )
+ if standard_logging_object is None:
+ return
+ langfuse_logger_to_use.log_event_on_langfuse(
+ start_time=start_time,
+ end_time=end_time,
+ response_obj=None,
+ user_id=kwargs.get("user", None),
+ status_message=standard_logging_object["error_str"],
+ level="ERROR",
+ kwargs=kwargs,
+ )
+ except Exception as e:
+ from litellm._logging import verbose_logger
+
+ verbose_logger.exception(
+ f"Langfuse Layer Error - Exception occurred while logging failure event: {str(e)}"
+ )
+ self.handle_callback_failure(callback_name="langfuse")
diff --git a/litellm/integrations/langsmith.py b/litellm/integrations/langsmith.py
index 5893f14105d..ebd005f8804 100644
--- a/litellm/integrations/langsmith.py
+++ b/litellm/integrations/langsmith.py
@@ -15,6 +15,10 @@ from pydantic import BaseModel # type: ignore
import litellm
from litellm._logging import verbose_logger
from litellm.integrations.custom_batch_logger import CustomBatchLogger
+from litellm.integrations.langsmith_mock_client import (
+ should_use_langsmith_mock,
+ create_mock_langsmith_client,
+)
from litellm.llms.custom_httpx.http_handler import (
get_async_httpx_client,
httpxSpecialProvider,
@@ -45,6 +49,12 @@ class LangsmithLogger(CustomBatchLogger):
):
self.flush_lock = asyncio.Lock()
super().__init__(**kwargs, flush_lock=self.flush_lock)
+ self.is_mock_mode = should_use_langsmith_mock()
+
+ if self.is_mock_mode:
+ create_mock_langsmith_client()
+ verbose_logger.debug("[LANGSMITH MOCK] LangSmith logger initialized in mock mode")
+
self.default_credentials = self.get_credentials_from_env(
langsmith_api_key=langsmith_api_key,
langsmith_project=langsmith_project,
@@ -388,6 +398,8 @@ class LangsmithLogger(CustomBatchLogger):
verbose_logger.debug(
"Sending batch of %s runs to Langsmith", len(elements_to_log)
)
+ if self.is_mock_mode:
+ verbose_logger.debug("[LANGSMITH MOCK] Mock mode enabled - API calls will be intercepted")
response = await self.async_httpx_client.post(
url=url,
json={"post": elements_to_log},
@@ -400,9 +412,14 @@ class LangsmithLogger(CustomBatchLogger):
f"Langsmith Error: {response.status_code} - {response.text}"
)
else:
- verbose_logger.debug(
- f"Batch of {len(self.log_queue)} runs successfully created"
- )
+ if self.is_mock_mode:
+ verbose_logger.debug(
+ f"[LANGSMITH MOCK] Batch of {len(elements_to_log)} runs successfully mocked"
+ )
+ else:
+ verbose_logger.debug(
+ f"Batch of {len(self.log_queue)} runs successfully created"
+ )
except httpx.HTTPStatusError as e:
verbose_logger.exception(
f"Langsmith HTTP Error: {e.response.status_code} - {e.response.text}"
diff --git a/litellm/integrations/langsmith_mock_client.py b/litellm/integrations/langsmith_mock_client.py
new file mode 100644
index 00000000000..ef602908231
--- /dev/null
+++ b/litellm/integrations/langsmith_mock_client.py
@@ -0,0 +1,29 @@
+"""
+Mock client for LangSmith integration testing.
+
+This module intercepts LangSmith API calls and returns successful mock responses,
+allowing full code execution without making actual network calls.
+
+Usage:
+ Set LANGSMITH_MOCK=true in environment variables or config to enable mock mode.
+"""
+
+from litellm.integrations.mock_client_factory import MockClientConfig, create_mock_client_factory
+
+# Create mock client using factory
+_config = MockClientConfig(
+ name="LANGSMITH",
+ env_var="LANGSMITH_MOCK",
+ default_latency_ms=100,
+ default_status_code=200,
+ default_json_data={"status": "success", "ids": ["mock-run-id"]},
+ url_matchers=[
+ ".smith.langchain.com",
+ "api.smith.langchain.com",
+ "smith.langchain.com",
+ ],
+ patch_async_handler=True,
+ patch_sync_client=False,
+)
+
+create_mock_langsmith_client, should_use_langsmith_mock = create_mock_client_factory(_config)
diff --git a/litellm/integrations/mock_client_factory.py b/litellm/integrations/mock_client_factory.py
new file mode 100644
index 00000000000..2f04fae9f76
--- /dev/null
+++ b/litellm/integrations/mock_client_factory.py
@@ -0,0 +1,216 @@
+"""
+Factory for creating mock HTTP clients for integration testing.
+
+This module provides a simple factory pattern to create mock clients that intercept
+API calls and return successful mock responses, allowing full code execution without
+making actual network calls.
+"""
+
+import httpx
+import json
+import asyncio
+from datetime import timedelta
+from typing import Dict, Optional, List, cast
+from dataclasses import dataclass
+
+from litellm._logging import verbose_logger
+
+
+@dataclass
+class MockClientConfig:
+ """Configuration for creating a mock client."""
+ name: str # e.g., "GCS", "LANGFUSE", "LANGSMITH", "DATADOG"
+ env_var: str # e.g., "GCS_MOCK", "LANGFUSE_MOCK"
+ default_latency_ms: int = 100 # Default mock latency in milliseconds
+ default_status_code: int = 200 # Default HTTP status code
+ default_json_data: Optional[Dict] = None # Default JSON response data
+ url_matchers: Optional[List[str]] = None # List of strings to match in URLs (e.g., ["storage.googleapis.com"])
+ patch_async_handler: bool = True # Whether to patch AsyncHTTPHandler.post
+ patch_sync_client: bool = False # Whether to patch httpx.Client.post
+ patch_http_handler: bool = False # Whether to patch HTTPHandler.post (for sync calls that use HTTPHandler)
+
+ def __post_init__(self):
+ """Ensure url_matchers is a list."""
+ if self.url_matchers is None:
+ self.url_matchers = []
+
+
+class MockResponse:
+ """Generic mock httpx.Response that satisfies API requirements."""
+
+ def __init__(self, status_code: int = 200, json_data: Optional[Dict] = None, url: Optional[str] = None, elapsed_seconds: float = 0.0):
+ self.status_code = status_code
+ self._json_data = json_data or {"status": "success"}
+ self.headers = httpx.Headers({})
+ self.is_success = status_code < 400
+ self.is_error = status_code >= 400
+ self.is_redirect = 300 <= status_code < 400
+ self.url = httpx.URL(url) if url else httpx.URL("")
+ self.elapsed = timedelta(seconds=elapsed_seconds)
+ self._text = json.dumps(self._json_data) if json_data else ""
+ self._content = self._text.encode("utf-8")
+
+ @property
+ def text(self) -> str:
+ """Return response text."""
+ return self._text
+
+ @property
+ def content(self) -> bytes:
+ """Return response content."""
+ return self._content
+
+ def json(self) -> Dict:
+ """Return JSON response data."""
+ return self._json_data
+
+ def read(self) -> bytes:
+ """Read response content."""
+ return self._content
+
+ def raise_for_status(self):
+ """Raise exception for error status codes."""
+ if self.status_code >= 400:
+ raise Exception(f"HTTP {self.status_code}")
+
+
+def _is_url_match(url, matchers: List[str]) -> bool:
+ """Check if URL matches any of the provided matchers."""
+ try:
+ parsed_url = httpx.URL(url) if isinstance(url, str) else url
+ url_str = str(parsed_url).lower()
+ hostname = parsed_url.host or ""
+
+ for matcher in matchers:
+ if matcher.lower() in url_str or matcher.lower() in hostname.lower():
+ return True
+
+ # Also check for localhost with matcher in path
+ if hostname in ("localhost", "127.0.0.1"):
+ for matcher in matchers:
+ if matcher.lower() in url_str:
+ return True
+
+ return False
+ except Exception:
+ return False
+
+
+def create_mock_client_factory(config: MockClientConfig): # noqa: PLR0915
+ """
+ Factory function that creates mock client functions based on configuration.
+
+ Returns:
+ tuple: (create_mock_client_func, should_use_mock_func)
+ """
+ # Store original methods for restoration
+ _original_async_handler_post = None
+ _original_sync_client_post = None
+ _original_http_handler_post = None
+ _mocks_initialized = False
+
+ # Calculate mock latency
+ import os
+ latency_env = f"{config.name.upper()}_MOCK_LATENCY_MS"
+ _MOCK_LATENCY_SECONDS = float(os.getenv(latency_env, str(config.default_latency_ms))) / 1000.0
+
+ # Create URL matcher function
+ def _is_mock_url(url) -> bool:
+ # url_matchers is guaranteed to be a list after __post_init__
+ return _is_url_match(url, cast(List[str], config.url_matchers))
+
+ # Create async handler mock
+ async def _mock_async_handler_post(self, url, data=None, json=None, params=None, headers=None, timeout=None, stream=False, logging_obj=None, files=None, content=None):
+ """Monkey-patched AsyncHTTPHandler.post that intercepts API calls."""
+ if isinstance(url, str) and _is_mock_url(url):
+ verbose_logger.info(f"[{config.name} MOCK] POST to {url}")
+ await asyncio.sleep(_MOCK_LATENCY_SECONDS)
+ return MockResponse(
+ status_code=config.default_status_code,
+ json_data=config.default_json_data,
+ url=url,
+ elapsed_seconds=_MOCK_LATENCY_SECONDS
+ )
+ if _original_async_handler_post is not None:
+ return await _original_async_handler_post(self, url=url, data=data, json=json, params=params, headers=headers, timeout=timeout, stream=stream, logging_obj=logging_obj, files=files, content=content)
+ raise RuntimeError("Original AsyncHTTPHandler.post not available")
+
+ # Create sync client mock
+ def _mock_sync_client_post(self, url, **kwargs):
+ """Monkey-patched httpx.Client.post that intercepts API calls."""
+ if _is_mock_url(url):
+ verbose_logger.info(f"[{config.name} MOCK] POST to {url} (sync)")
+ return MockResponse(
+ status_code=config.default_status_code,
+ json_data=config.default_json_data,
+ url=url,
+ elapsed_seconds=_MOCK_LATENCY_SECONDS
+ )
+ if _original_sync_client_post is not None:
+ return _original_sync_client_post(self, url, **kwargs)
+
+ # Create HTTPHandler mock (for sync calls that use HTTPHandler.post)
+ def _mock_http_handler_post(self, url, data=None, json=None, params=None, headers=None, timeout=None, stream=False, files=None, content=None, logging_obj=None):
+ """Monkey-patched HTTPHandler.post that intercepts API calls."""
+ if isinstance(url, str) and _is_mock_url(url):
+ verbose_logger.info(f"[{config.name} MOCK] POST to {url}")
+ import time
+ time.sleep(_MOCK_LATENCY_SECONDS)
+ return MockResponse(
+ status_code=config.default_status_code,
+ json_data=config.default_json_data,
+ url=url,
+ elapsed_seconds=_MOCK_LATENCY_SECONDS
+ )
+ if _original_http_handler_post is not None:
+ return _original_http_handler_post(self, url=url, data=data, json=json, params=params, headers=headers, timeout=timeout, stream=stream, files=files, content=content, logging_obj=logging_obj)
+ raise RuntimeError("Original HTTPHandler.post not available")
+
+ # Create mock client initialization function
+ def create_mock_client():
+ """Initialize the mock client by patching HTTP handlers."""
+ nonlocal _original_async_handler_post, _original_sync_client_post, _original_http_handler_post, _mocks_initialized
+
+ if _mocks_initialized:
+ return
+
+ verbose_logger.debug(f"[{config.name} MOCK] Initializing {config.name} mock client...")
+
+ if config.patch_async_handler and _original_async_handler_post is None:
+ from litellm.llms.custom_httpx.http_handler import AsyncHTTPHandler
+ _original_async_handler_post = AsyncHTTPHandler.post
+ AsyncHTTPHandler.post = _mock_async_handler_post # type: ignore
+ verbose_logger.debug(f"[{config.name} MOCK] Patched AsyncHTTPHandler.post")
+
+ if config.patch_sync_client and _original_sync_client_post is None:
+ _original_sync_client_post = httpx.Client.post
+ httpx.Client.post = _mock_sync_client_post # type: ignore
+ verbose_logger.debug(f"[{config.name} MOCK] Patched httpx.Client.post")
+
+ if config.patch_http_handler and _original_http_handler_post is None:
+ from litellm.llms.custom_httpx.http_handler import HTTPHandler
+ _original_http_handler_post = HTTPHandler.post
+ HTTPHandler.post = _mock_http_handler_post # type: ignore
+ verbose_logger.debug(f"[{config.name} MOCK] Patched HTTPHandler.post")
+
+ verbose_logger.debug(f"[{config.name} MOCK] Mock latency set to {_MOCK_LATENCY_SECONDS*1000:.0f}ms")
+ verbose_logger.debug(f"[{config.name} MOCK] {config.name} mock client initialization complete")
+
+ _mocks_initialized = True
+
+ # Create should_use_mock function
+ def should_use_mock() -> bool:
+ """Determine if mock mode should be enabled."""
+ import os
+ from litellm.secret_managers.main import str_to_bool
+
+ mock_mode = os.getenv(config.env_var, "false")
+ result = str_to_bool(mock_mode)
+ result = bool(result) if result is not None else False
+
+ if result:
+ verbose_logger.info(f"{config.name} Mock Mode: ENABLED - API calls will be mocked")
+
+ return result
+
+ return create_mock_client, should_use_mock
diff --git a/litellm/integrations/opentelemetry.py b/litellm/integrations/opentelemetry.py
index 93d631eb0f2..296a88f9a0b 100644
--- a/litellm/integrations/opentelemetry.py
+++ b/litellm/integrations/opentelemetry.py
@@ -17,6 +17,10 @@ from litellm.types.utils import (
StandardCallbackDynamicParams,
StandardLoggingPayload,
)
+from litellm.integrations._types.open_inference import (
+ OpenInferenceSpanKindValues,
+ SpanAttributes,
+)
# OpenTelemetry imports moved to individual functions to avoid import errors when not installed
@@ -140,6 +144,7 @@ class OpenTelemetry(CustomLogger):
self.OTEL_EXPORTER = self.config.exporter
self.OTEL_ENDPOINT = self.config.endpoint
self.OTEL_HEADERS = self.config.headers
+ self._tracer_provider_cache: Dict[str, Any] = {}
self._init_tracing(tracer_provider)
_debug_otel = str(os.getenv("DEBUG_OTEL", "False")).lower()
@@ -594,9 +599,9 @@ class OpenTelemetry(CustomLogger):
def _get_dynamic_otel_headers_from_kwargs(self, kwargs) -> Optional[dict]:
"""Extract dynamic headers from kwargs if available."""
- standard_callback_dynamic_params: Optional[StandardCallbackDynamicParams] = (
- kwargs.get("standard_callback_dynamic_params")
- )
+ standard_callback_dynamic_params: Optional[
+ StandardCallbackDynamicParams
+ ] = kwargs.get("standard_callback_dynamic_params")
if not standard_callback_dynamic_params:
return None
@@ -611,12 +616,22 @@ class OpenTelemetry(CustomLogger):
"""Create a temporary tracer with dynamic headers for this request only."""
from opentelemetry.sdk.trace import TracerProvider
+ # Prevents thread exhaustion by reusing providers for the same credential sets (e.g. per-team keys)
+ cache_key = str(sorted(dynamic_headers.items()))
+ if cache_key in self._tracer_provider_cache:
+ return self._tracer_provider_cache[cache_key].get_tracer(
+ LITELLM_TRACER_NAME
+ )
+
# Create a temporary tracer provider with dynamic headers
temp_provider = TracerProvider(resource=self._get_litellm_resource(self.config))
temp_provider.add_span_processor(
self._get_span_processor(dynamic_headers=dynamic_headers)
)
+ # Store in cache for reuse
+ self._tracer_provider_cache[cache_key] = temp_provider
+
return temp_provider.get_tracer(LITELLM_TRACER_NAME)
def construct_dynamic_otel_headers(
@@ -660,6 +675,12 @@ class OpenTelemetry(CustomLogger):
self._maybe_log_raw_request(
kwargs, response_obj, start_time, end_time, span
)
+ # Ensure proxy-request parent span is annotated with the actual operation kind
+ if (
+ parent_span is not None
+ and parent_span.name == LITELLM_PROXY_REQUEST_SPAN_NAME
+ ):
+ self.set_attributes(parent_span, kwargs, response_obj)
else:
# Do not create primary span (keep hierarchy shallow when parent exists)
from opentelemetry.trace import Status, StatusCode
@@ -987,10 +1008,11 @@ class OpenTelemetry(CustomLogger):
# TODO: Refactor to use the proper OTEL Logs API instead of directly creating SDK LogRecords
from opentelemetry._logs import SeverityNumber, get_logger, get_logger_provider
+
try:
from opentelemetry.sdk._logs import LogRecord as SdkLogRecord # type: ignore[attr-defined] # OTEL < 1.39.0
except ImportError:
- from opentelemetry.sdk._logs._internal import LogRecord as SdkLogRecord # OTEL >= 1.39.0
+ from opentelemetry.sdk._logs._internal import LogRecord as SdkLogRecord # type: ignore[attr-defined, no-redef] # OTEL >= 1.39.0
otel_logger = get_logger(LITELLM_LOGGER_NAME)
@@ -1106,6 +1128,12 @@ class OpenTelemetry(CustomLogger):
context=context,
)
+ self.safe_set_attribute(
+ span=guardrail_span,
+ key=SpanAttributes.OPENINFERENCE_SPAN_KIND,
+ value=OpenInferenceSpanKindValues.GUARDRAIL.value,
+ )
+
self.safe_set_attribute(
span=guardrail_span,
key="guardrail_name",
@@ -1592,7 +1620,6 @@ class OpenTelemetry(CustomLogger):
for idx, choice in enumerate(response_obj.get("choices")):
if choice.get("finish_reason"):
-
message = choice.get("message")
tool_calls = message.get("tool_calls")
if tool_calls:
@@ -1605,6 +1632,9 @@ class OpenTelemetry(CustomLogger):
)
except Exception as e:
+ self.handle_callback_failure(
+ callback_name=self.callback_name or "opentelemetry"
+ )
verbose_logger.exception(
"OpenTelemetry logging error in set_attributes %s", str(e)
)
@@ -1695,6 +1725,7 @@ class OpenTelemetry(CustomLogger):
def set_raw_request_attributes(self, span: Span, kwargs, response_obj):
try:
+ self.set_attributes(span, kwargs, response_obj)
kwargs.get("optional_params", {})
litellm_params = kwargs.get("litellm_params", {}) or {}
custom_llm_provider = litellm_params.get("custom_llm_provider", "Unknown")
diff --git a/litellm/integrations/posthog.py b/litellm/integrations/posthog.py
index 468b1a441fb..dd7c3627b87 100644
--- a/litellm/integrations/posthog.py
+++ b/litellm/integrations/posthog.py
@@ -17,6 +17,10 @@ from typing import Any, Dict, Optional, Tuple
from litellm._logging import verbose_logger
from litellm._uuid import uuid
from litellm.integrations.custom_batch_logger import CustomBatchLogger
+from litellm.integrations.posthog_mock_client import (
+ should_use_posthog_mock,
+ create_mock_posthog_client,
+)
from litellm.llms.custom_httpx.http_handler import (
_get_httpx_client,
get_async_httpx_client,
@@ -40,6 +44,12 @@ class PostHogLogger(CustomBatchLogger):
"""
try:
verbose_logger.debug("PostHog: in init posthog logger")
+
+ self.is_mock_mode = should_use_posthog_mock()
+ if self.is_mock_mode:
+ create_mock_posthog_client()
+ verbose_logger.debug("[POSTHOG MOCK] PostHog logger initialized in mock mode")
+
if os.getenv("POSTHOG_API_KEY", None) is None:
raise Exception("POSTHOG_API_KEY is not set, set 'POSTHOG_API_KEY=<>'")
@@ -100,7 +110,10 @@ class PostHogLogger(CustomBatchLogger):
f"Response from PostHog API status_code: {response.status_code}, text: {response.text}"
)
- verbose_logger.debug("PostHog: Sync event successfully sent")
+ if self.is_mock_mode:
+ verbose_logger.debug("[POSTHOG MOCK] Sync event successfully mocked")
+ else:
+ verbose_logger.debug("PostHog: Sync event successfully sent")
except Exception as e:
verbose_logger.exception(f"PostHog Sync Layer Error - {str(e)}")
@@ -320,6 +333,9 @@ class PostHogLogger(CustomBatchLogger):
verbose_logger.debug(
f"PostHog: Sending batch of {len(self.log_queue)} events"
)
+
+ if self.is_mock_mode:
+ verbose_logger.debug("[POSTHOG MOCK] Mock mode enabled - API calls will be intercepted")
# Group events by credentials for batch sending
batches_by_credentials: Dict[tuple[str, str], list] = {}
@@ -350,9 +366,12 @@ class PostHogLogger(CustomBatchLogger):
f"Response from PostHog API status_code: {response.status_code}, text: {response.text}"
)
- verbose_logger.debug(
- f"PostHog: Batch of {len(self.log_queue)} events successfully sent"
- )
+ if self.is_mock_mode:
+ verbose_logger.debug(f"[POSTHOG MOCK] Batch of {len(self.log_queue)} events successfully mocked")
+ else:
+ verbose_logger.debug(
+ f"PostHog: Batch of {len(self.log_queue)} events successfully sent"
+ )
except Exception as e:
verbose_logger.exception(f"PostHog Error sending batch API - {str(e)}")
@@ -429,9 +448,14 @@ class PostHogLogger(CustomBatchLogger):
f"PostHog: Failed to flush on exit - status {response.status_code}"
)
- verbose_logger.debug(
- f"PostHog: Successfully flushed {len(self.log_queue)} events on exit"
- )
+ if self.is_mock_mode:
+ verbose_logger.debug(
+ f"[POSTHOG MOCK] Successfully flushed {len(self.log_queue)} events on exit"
+ )
+ else:
+ verbose_logger.debug(
+ f"PostHog: Successfully flushed {len(self.log_queue)} events on exit"
+ )
self.log_queue.clear()
except Exception as e:
diff --git a/litellm/integrations/posthog_mock_client.py b/litellm/integrations/posthog_mock_client.py
new file mode 100644
index 00000000000..b713587ed6f
--- /dev/null
+++ b/litellm/integrations/posthog_mock_client.py
@@ -0,0 +1,30 @@
+"""
+Mock httpx client for PostHog integration testing.
+
+This module intercepts PostHog API calls and returns successful mock responses,
+allowing full code execution without making actual network calls.
+
+Usage:
+ Set POSTHOG_MOCK=true in environment variables or config to enable mock mode.
+"""
+
+from litellm.integrations.mock_client_factory import MockClientConfig, create_mock_client_factory
+
+# Create mock client using factory
+_config = MockClientConfig(
+ name="POSTHOG",
+ env_var="POSTHOG_MOCK",
+ default_latency_ms=100,
+ default_status_code=200,
+ default_json_data={"status": "success"},
+ url_matchers=[
+ ".posthog.com",
+ "posthog.com",
+ "us.i.posthog.com",
+ "app.posthog.com",
+ ],
+ patch_async_handler=True,
+ patch_sync_client=True,
+)
+
+create_mock_posthog_client, should_use_posthog_mock = create_mock_client_factory(_config)
diff --git a/litellm/integrations/prometheus.py b/litellm/integrations/prometheus.py
index bafb0d88c82..0a61dab0680 100644
--- a/litellm/integrations/prometheus.py
+++ b/litellm/integrations/prometheus.py
@@ -1,6 +1,7 @@
# used for /metrics endpoint on LiteLLM Proxy
#### What this does ####
# On success, log events to Prometheus
+import asyncio
import os
import sys
from datetime import datetime, timedelta
@@ -229,14 +230,18 @@ class PrometheusLogger(CustomLogger):
self.litellm_remaining_api_key_requests_for_model = self._gauge_factory(
"litellm_remaining_api_key_requests_for_model",
"Remaining Requests API Key can make for model (model based rpm limit on key)",
- labelnames=["hashed_api_key", "api_key_alias", "model"],
+ labelnames=self.get_labels_for_metric(
+ "litellm_remaining_api_key_requests_for_model"
+ ),
)
# Remaining MODEL TPM limit for API Key
self.litellm_remaining_api_key_tokens_for_model = self._gauge_factory(
"litellm_remaining_api_key_tokens_for_model",
"Remaining Tokens API Key can make for model (model based tpm limit on key)",
- labelnames=["hashed_api_key", "api_key_alias", "model"],
+ labelnames=self.get_labels_for_metric(
+ "litellm_remaining_api_key_tokens_for_model"
+ ),
)
########################################
@@ -312,6 +317,18 @@ class PrometheusLogger(CustomLogger):
labelnames=self.get_labels_for_metric("litellm_deployment_state"),
)
+ self.litellm_deployment_tpm_limit = self._gauge_factory(
+ "litellm_deployment_tpm_limit",
+ "Deployment TPM limit found in config",
+ labelnames=self.get_labels_for_metric("litellm_deployment_tpm_limit"),
+ )
+
+ self.litellm_deployment_rpm_limit = self._gauge_factory(
+ "litellm_deployment_rpm_limit",
+ "Deployment RPM limit found in config",
+ labelnames=self.get_labels_for_metric("litellm_deployment_rpm_limit"),
+ )
+
self.litellm_deployment_cooled_down = self._counter_factory(
"litellm_deployment_cooled_down",
"LLM Deployment Analytics - Number of times a deployment has been cooled down by LiteLLM load balancing logic. exception_status is the status of the exception that caused the deployment to be cooled down",
@@ -373,15 +390,9 @@ class PrometheusLogger(CustomLogger):
self.litellm_llm_api_failed_requests_metric = self._counter_factory(
name="litellm_llm_api_failed_requests_metric",
documentation="deprecated - use litellm_proxy_failed_requests_metric",
- labelnames=[
- "end_user",
- "hashed_api_key",
- "api_key_alias",
- "model",
- "team",
- "team_alias",
- "user",
- ],
+ labelnames=self.get_labels_for_metric(
+ "litellm_llm_api_failed_requests_metric"
+ ),
)
self.litellm_requests_metric = self._counter_factory(
@@ -891,7 +902,7 @@ class PrometheusLogger(CustomLogger):
model = kwargs.get("model", "")
litellm_params = kwargs.get("litellm_params", {}) or {}
- _metadata = litellm_params.get("metadata", {})
+ _metadata = litellm_params.get("metadata") or {}
get_end_user_id_for_cost_tracking = _get_cached_end_user_id_for_cost_tracking()
end_user_id = get_end_user_id_for_cost_tracking(
@@ -954,6 +965,8 @@ class PrometheusLogger(CustomLogger):
route=standard_logging_payload["metadata"].get(
"user_api_key_request_route"
),
+ client_ip=standard_logging_payload["metadata"].get("requester_ip_address"),
+ user_agent=standard_logging_payload["metadata"].get("user_agent"),
)
if (
@@ -1011,6 +1024,7 @@ class PrometheusLogger(CustomLogger):
user_api_key_alias=user_api_key_alias,
kwargs=kwargs,
metadata=_metadata,
+ model_id=enum_values.model_id,
)
# set latency metrics
@@ -1165,49 +1179,44 @@ class PrometheusLogger(CustomLogger):
response_cost: float,
user_id: Optional[str] = None,
):
- _team_spend = litellm_params.get("metadata", {}).get(
- "user_api_key_team_spend", None
- )
- _team_max_budget = litellm_params.get("metadata", {}).get(
- "user_api_key_team_max_budget", None
- )
+ _metadata = litellm_params.get("metadata") or {}
+ _team_spend = _metadata.get("user_api_key_team_spend", None)
+ _team_max_budget = _metadata.get("user_api_key_team_max_budget", None)
- _api_key_spend = litellm_params.get("metadata", {}).get(
- "user_api_key_spend", None
- )
- _api_key_max_budget = litellm_params.get("metadata", {}).get(
- "user_api_key_max_budget", None
- )
+ _api_key_spend = _metadata.get("user_api_key_spend", None)
+ _api_key_max_budget = _metadata.get("user_api_key_max_budget", None)
- _user_spend = litellm_params.get("metadata", {}).get(
- "user_api_key_user_spend", None
- )
- _user_max_budget = litellm_params.get("metadata", {}).get(
- "user_api_key_user_max_budget", None
- )
+ _user_spend = _metadata.get("user_api_key_user_spend", None)
+ _user_max_budget = _metadata.get("user_api_key_user_max_budget", None)
- await self._set_api_key_budget_metrics_after_api_request(
- user_api_key=user_api_key,
- user_api_key_alias=user_api_key_alias,
- response_cost=response_cost,
- key_max_budget=_api_key_max_budget,
- key_spend=_api_key_spend,
- )
-
- await self._set_team_budget_metrics_after_api_request(
- user_api_team=user_api_team,
- user_api_team_alias=user_api_team_alias,
- team_spend=_team_spend,
- team_max_budget=_team_max_budget,
- response_cost=response_cost,
- )
-
- await self._set_user_budget_metrics_after_api_request(
- user_id=user_id,
- user_spend=_user_spend,
- user_max_budget=_user_max_budget,
- response_cost=response_cost,
+ results = await asyncio.gather(
+ self._set_api_key_budget_metrics_after_api_request(
+ user_api_key=user_api_key,
+ user_api_key_alias=user_api_key_alias,
+ response_cost=response_cost,
+ key_max_budget=_api_key_max_budget,
+ key_spend=_api_key_spend,
+ ),
+ self._set_team_budget_metrics_after_api_request(
+ user_api_team=user_api_team,
+ user_api_team_alias=user_api_team_alias,
+ team_spend=_team_spend,
+ team_max_budget=_team_max_budget,
+ response_cost=response_cost,
+ ),
+ self._set_user_budget_metrics_after_api_request(
+ user_id=user_id,
+ user_spend=_user_spend,
+ user_max_budget=_user_max_budget,
+ response_cost=response_cost,
+ ),
+ return_exceptions=True,
)
+ for i, r in enumerate(results):
+ if isinstance(r, Exception):
+ verbose_logger.debug(
+ f"[Non-Blocking] Prometheus: Budget metric lookup {['key', 'team', 'user'][i]} failed: {r}"
+ )
def _increment_top_level_request_and_spend_metrics(
self,
@@ -1245,6 +1254,7 @@ class PrometheusLogger(CustomLogger):
user_api_key_alias: Optional[str],
kwargs: dict,
metadata: dict,
+ model_id: Optional[str] = None,
):
from litellm.proxy.common_utils.callback_utils import (
get_model_group_from_litellm_kwargs,
@@ -1266,11 +1276,11 @@ class PrometheusLogger(CustomLogger):
)
self.litellm_remaining_api_key_requests_for_model.labels(
- user_api_key, user_api_key_alias, model_group
+ user_api_key, user_api_key_alias, model_group, model_id
).set(remaining_requests)
self.litellm_remaining_api_key_tokens_for_model.labels(
- user_api_key, user_api_key_alias, model_group
+ user_api_key, user_api_key_alias, model_group, model_id
).set(remaining_tokens)
def _set_latency_metrics(
@@ -1296,12 +1306,14 @@ class PrometheusLogger(CustomLogger):
time_to_first_token_seconds is not None
and kwargs.get("stream", False) is True # only emit for streaming requests
):
+ _ttft_labels = prometheus_label_factory(
+ supported_enum_labels=self.get_labels_for_metric(
+ metric_name="litellm_llm_api_time_to_first_token_metric"
+ ),
+ enum_values=enum_values,
+ )
self.litellm_llm_api_time_to_first_token_metric.labels(
- model,
- user_api_key,
- user_api_key_alias,
- user_api_team,
- user_api_team_alias,
+ **_ttft_labels
).observe(time_to_first_token_seconds)
else:
verbose_logger.debug(
@@ -1341,7 +1353,7 @@ class PrometheusLogger(CustomLogger):
# request queue time (time from arrival to processing start)
_litellm_params = kwargs.get("litellm_params", {}) or {}
- queue_time_seconds = _litellm_params.get("metadata", {}).get(
+ queue_time_seconds = (_litellm_params.get("metadata") or {}).get(
"queue_time_seconds"
)
if queue_time_seconds is not None and queue_time_seconds >= 0:
@@ -1365,14 +1377,14 @@ class PrometheusLogger(CustomLogger):
standard_logging_payload: StandardLoggingPayload = kwargs.get(
"standard_logging_object", {}
)
-
+
if self._should_skip_metrics_for_invalid_key(
kwargs=kwargs, standard_logging_payload=standard_logging_payload
):
return
-
+
model = kwargs.get("model", "")
-
+
litellm_params = kwargs.get("litellm_params", {}) or {}
get_end_user_id_for_cost_tracking = _get_cached_end_user_id_for_cost_tracking()
@@ -1396,6 +1408,7 @@ class PrometheusLogger(CustomLogger):
user_api_team,
user_api_team_alias,
user_id,
+ standard_logging_payload.get("model_id", ""),
).inc()
self.set_llm_deployment_failure_metrics(kwargs)
except Exception as e:
@@ -1413,49 +1426,57 @@ class PrometheusLogger(CustomLogger):
) -> Optional[int]:
"""
Extract HTTP status code from various input formats for validation.
-
+
This is a centralized helper to extract status code from different
callback function signatures. Handles both ProxyException (uses 'code')
and standard exceptions (uses 'status_code').
-
+
Args:
kwargs: Dictionary potentially containing 'exception' key
enum_values: Object with 'status_code' attribute
exception: Exception object to extract status code from directly
-
+
Returns:
Status code as integer if found, None otherwise
"""
status_code = None
-
+
# Try from enum_values first (most common in our callbacks)
- if enum_values and hasattr(enum_values, "status_code") and enum_values.status_code:
+ if (
+ enum_values
+ and hasattr(enum_values, "status_code")
+ and enum_values.status_code
+ ):
try:
status_code = int(enum_values.status_code)
except (ValueError, TypeError):
pass
-
+
if not status_code and exception:
# ProxyException uses 'code' attribute, other exceptions may use 'status_code'
- status_code = getattr(exception, "status_code", None) or getattr(exception, "code", None)
+ status_code = getattr(exception, "status_code", None) or getattr(
+ exception, "code", None
+ )
if status_code is not None:
try:
status_code = int(status_code)
except (ValueError, TypeError):
status_code = None
-
+
if not status_code and kwargs:
exception_in_kwargs = kwargs.get("exception")
if exception_in_kwargs:
- status_code = getattr(exception_in_kwargs, "status_code", None) or getattr(exception_in_kwargs, "code", None)
+ status_code = getattr(
+ exception_in_kwargs, "status_code", None
+ ) or getattr(exception_in_kwargs, "code", None)
if status_code is not None:
try:
status_code = int(status_code)
except (ValueError, TypeError):
status_code = None
-
+
return status_code
-
+
def _is_invalid_api_key_request(
self,
status_code: Optional[int],
@@ -1463,23 +1484,23 @@ class PrometheusLogger(CustomLogger):
) -> bool:
"""
Determine if a request has an invalid API key based on status code and exception.
-
+
This method prevents invalid authentication attempts from being recorded in
Prometheus metrics. A 401 status code is the definitive indicator of authentication
failure. Additionally, we check exception messages for authentication error patterns
to catch cases where the exception hasn't been converted to a ProxyException yet.
-
+
Args:
status_code: HTTP status code (401 indicates authentication error)
exception: Exception object to check for auth-related error messages
-
+
Returns:
True if the request has an invalid API key and metrics should be skipped,
False otherwise
"""
if status_code == 401:
return True
-
+
# Handle cases where AssertionError is raised before conversion to ProxyException
if exception is not None:
exception_str = str(exception).lower()
@@ -1492,9 +1513,9 @@ class PrometheusLogger(CustomLogger):
]
if any(pattern in exception_str for pattern in auth_error_patterns):
return True
-
+
return False
-
+
def _should_skip_metrics_for_invalid_key(
self,
kwargs: Optional[dict] = None,
@@ -1505,18 +1526,18 @@ class PrometheusLogger(CustomLogger):
) -> bool:
"""
Determine if Prometheus metrics should be skipped for invalid API key requests.
-
+
This is a centralized validation method that extracts status code and exception
information from various callback function signatures and determines if the request
represents an invalid API key attempt that should be filtered from metrics.
-
+
Args:
kwargs: Dictionary potentially containing exception and other data
user_api_key_dict: User API key authentication object (currently unused)
enum_values: Object with status_code attribute
standard_logging_payload: Standard logging payload dictionary
exception: Exception object to check directly
-
+
Returns:
True if metrics should be skipped (invalid key detected), False otherwise
"""
@@ -1525,17 +1546,17 @@ class PrometheusLogger(CustomLogger):
enum_values=enum_values,
exception=exception,
)
-
+
if exception is None and kwargs:
exception = kwargs.get("exception")
-
+
if self._is_invalid_api_key_request(status_code, exception=exception):
verbose_logger.debug(
"Skipping Prometheus metrics for invalid API key request: "
f"status_code={status_code}, exception={type(exception).__name__ if exception else None}"
)
return True
-
+
return False
async def async_post_call_failure_hook(
@@ -1576,6 +1597,10 @@ class PrometheusLogger(CustomLogger):
litellm_params=request_data,
proxy_server_request=request_data.get("proxy_server_request", {}),
)
+ _metadata = request_data.get("metadata", {}) or {}
+ model_id = _metadata.get("model_info", {}).get("id") or request_data.get(
+ "model_info", {}
+ ).get("id")
enum_values = UserAPIKeyLabelValues(
end_user=user_api_key_dict.end_user_id,
user=user_api_key_dict.user_id,
@@ -1590,6 +1615,9 @@ class PrometheusLogger(CustomLogger):
exception_class=self._get_exception_class_name(original_exception),
tags=_tags,
route=user_api_key_dict.request_route,
+ client_ip=_metadata.get("requester_ip_address"),
+ user_agent=_metadata.get("user_agent"),
+ model_id=model_id,
)
_labels = prometheus_label_factory(
supported_enum_labels=self.get_labels_for_metric(
@@ -1629,6 +1657,7 @@ class PrometheusLogger(CustomLogger):
):
return
+ _metadata = data.get("metadata", {}) or {}
enum_values = UserAPIKeyLabelValues(
end_user=user_api_key_dict.end_user_id,
hashed_api_key=user_api_key_dict.api_key,
@@ -1644,6 +1673,8 @@ class PrometheusLogger(CustomLogger):
litellm_params=data,
proxy_server_request=data.get("proxy_server_request", {}),
),
+ client_ip=_metadata.get("requester_ip_address"),
+ user_agent=_metadata.get("user_agent"),
)
_labels = prometheus_label_factory(
supported_enum_labels=self.get_labels_for_metric(
@@ -1659,6 +1690,108 @@ class PrometheusLogger(CustomLogger):
)
pass
+ def _safe_get(self, obj: Any, key: str, default: Any = None) -> Any:
+ """Get value from dict or Pydantic model."""
+ if obj is None:
+ return default
+ if isinstance(obj, dict):
+ return obj.get(key, default)
+ return getattr(obj, key, default)
+
+ def _extract_deployment_failure_label_values(
+ self, request_kwargs: dict
+ ) -> Dict[str, Optional[str]]:
+ """
+ Extract label values for deployment failure metrics from all available
+ sources in request_kwargs. Falls back to litellm_params metadata and
+ user_api_key_auth when standard_logging_payload has None values.
+ """
+ standard_logging_payload = (
+ request_kwargs.get("standard_logging_object", {}) or {}
+ )
+ _litellm_params = request_kwargs.get("litellm_params", {}) or {}
+ _metadata_raw = self._safe_get(standard_logging_payload, "metadata") or {}
+ if isinstance(_metadata_raw, dict):
+ _metadata = _metadata_raw
+ else:
+ _metadata = {
+ "user_api_key_alias": getattr(
+ _metadata_raw, "user_api_key_alias", None
+ ),
+ "user_api_key_team_id": getattr(
+ _metadata_raw, "user_api_key_team_id", None
+ ),
+ "user_api_key_team_alias": getattr(
+ _metadata_raw, "user_api_key_team_alias", None
+ ),
+ "user_api_key_hash": getattr(_metadata_raw, "user_api_key_hash", None),
+ "requester_ip_address": getattr(
+ _metadata_raw, "requester_ip_address", None
+ ),
+ "user_agent": getattr(_metadata_raw, "user_agent", None),
+ }
+ _litellm_params_metadata = _litellm_params.get("metadata", {}) or {}
+
+ # Extract user_api_key_auth if present (proxy injects this, skipped in merge)
+ user_api_key_auth = _litellm_params_metadata.get("user_api_key_auth")
+
+ def _get_api_key_alias() -> Optional[str]:
+ val = _metadata.get("user_api_key_alias")
+ if val is not None:
+ return val
+ val = _litellm_params_metadata.get("user_api_key_alias")
+ if val is not None:
+ return val
+ if user_api_key_auth is not None:
+ return getattr(user_api_key_auth, "key_alias", None)
+ return None
+
+ def _get_team_id() -> Optional[str]:
+ val = _metadata.get("user_api_key_team_id")
+ if val is not None:
+ return val
+ val = _litellm_params_metadata.get("user_api_key_team_id")
+ if val is not None:
+ return val
+ if user_api_key_auth is not None:
+ return getattr(user_api_key_auth, "team_id", None)
+ return None
+
+ def _get_team_alias() -> Optional[str]:
+ val = _metadata.get("user_api_key_team_alias")
+ if val is not None:
+ return val
+ val = _litellm_params_metadata.get("user_api_key_team_alias")
+ if val is not None:
+ return val
+ if user_api_key_auth is not None:
+ return getattr(user_api_key_auth, "team_alias", None)
+ return None
+
+ def _get_hashed_api_key() -> Optional[str]:
+ val = _metadata.get("user_api_key_hash")
+ if val is not None:
+ return val
+ val = _litellm_params_metadata.get("user_api_key_hash")
+ if val is not None:
+ return val
+ if user_api_key_auth is not None:
+ return getattr(user_api_key_auth, "api_key", None) or getattr(
+ user_api_key_auth, "api_key_hash", None
+ )
+ return None
+
+ return {
+ "api_key_alias": _get_api_key_alias(),
+ "team": _get_team_id(),
+ "team_alias": _get_team_alias(),
+ "hashed_api_key": _get_hashed_api_key(),
+ "client_ip": _metadata.get("requester_ip_address")
+ or _litellm_params_metadata.get("requester_ip_address"),
+ "user_agent": _metadata.get("user_agent")
+ or _litellm_params_metadata.get("user_agent"),
+ }
+
def set_llm_deployment_failure_metrics(self, request_kwargs: dict):
"""
Sets Failure metrics when an LLM API call fails
@@ -1683,16 +1816,59 @@ class PrometheusLogger(CustomLogger):
model_id = standard_logging_payload.get("model_id", None)
exception = request_kwargs.get("exception", None)
+ # Fallback: model_id from litellm_metadata.model_info
+ if model_id is None:
+ _model_info = (
+ (_litellm_params.get("litellm_metadata") or {}).get("model_info")
+ or (_litellm_params.get("metadata") or {}).get("model_info")
+ or {}
+ )
+ model_id = _model_info.get("id")
+
+ # Fallback: model_group from litellm_metadata
+ if model_group is None:
+ model_group = (_litellm_params.get("litellm_metadata") or {}).get(
+ "model_group"
+ ) or (_litellm_params.get("metadata") or {}).get("model_group")
+
llm_provider = _litellm_params.get("custom_llm_provider", None)
-
+
if self._should_skip_metrics_for_invalid_key(
kwargs=request_kwargs,
standard_logging_payload=standard_logging_payload,
):
return
- hashed_api_key = standard_logging_payload.get("metadata", {}).get(
+
+ # Extract context labels from all available sources (fix for None labels)
+ fallback_values = self._extract_deployment_failure_label_values(
+ request_kwargs
+ )
+ _metadata = standard_logging_payload.get("metadata", {}) or {}
+ hashed_api_key = fallback_values.get("hashed_api_key") or _metadata.get(
"user_api_key_hash"
)
+ api_key_alias = fallback_values.get("api_key_alias") or _metadata.get(
+ "user_api_key_alias"
+ )
+ team = fallback_values.get("team") or _metadata.get("user_api_key_team_id")
+ team_alias = fallback_values.get("team_alias") or _metadata.get(
+ "user_api_key_team_alias"
+ )
+ client_ip = fallback_values.get("client_ip") or _metadata.get(
+ "requester_ip_address"
+ )
+ user_agent = fallback_values.get("user_agent") or _metadata.get(
+ "user_agent"
+ )
+
+ # exception_status: prefer status_code, fallback to exception class for known types
+ exception_status = None
+ if exception is not None:
+ exception_status = str(getattr(exception, "status_code", None))
+ if exception_status == "None" or not exception_status:
+ code = getattr(exception, "code", None)
+ if code is not None:
+ exception_status = str(code)
# Create enum_values for the label factory (always create for use in different metrics)
enum_values = UserAPIKeyLabelValues(
@@ -1700,22 +1876,18 @@ class PrometheusLogger(CustomLogger):
model_id=model_id,
api_base=api_base,
api_provider=llm_provider,
- exception_status=(
- str(getattr(exception, "status_code", None)) if exception else None
- ),
+ exception_status=exception_status,
exception_class=(
self._get_exception_class_name(exception) if exception else None
),
- requested_model=model_group,
+ requested_model=model_group or litellm_model_name,
hashed_api_key=hashed_api_key,
- api_key_alias=standard_logging_payload["metadata"][
- "user_api_key_alias"
- ],
- team=standard_logging_payload["metadata"]["user_api_key_team_id"],
- team_alias=standard_logging_payload["metadata"][
- "user_api_key_team_alias"
- ],
+ api_key_alias=api_key_alias,
+ team=team,
+ team_alias=team_alias,
tags=standard_logging_payload.get("request_tags", []),
+ client_ip=client_ip,
+ user_agent=user_agent,
)
"""
@@ -1753,6 +1925,49 @@ class PrometheusLogger(CustomLogger):
)
)
+ def _set_deployment_tpm_rpm_limit_metrics(
+ self,
+ model_info: dict,
+ litellm_params: dict,
+ litellm_model_name: Optional[str],
+ model_id: Optional[str],
+ api_base: Optional[str],
+ llm_provider: Optional[str],
+ ):
+ """
+ Set the deployment TPM and RPM limits metrics
+ """
+ tpm = model_info.get("tpm") or litellm_params.get("tpm")
+ rpm = model_info.get("rpm") or litellm_params.get("rpm")
+
+ if tpm is not None:
+ _labels = prometheus_label_factory(
+ supported_enum_labels=self.get_labels_for_metric(
+ metric_name="litellm_deployment_tpm_limit"
+ ),
+ enum_values=UserAPIKeyLabelValues(
+ litellm_model_name=litellm_model_name,
+ model_id=model_id,
+ api_base=api_base,
+ api_provider=llm_provider,
+ ),
+ )
+ self.litellm_deployment_tpm_limit.labels(**_labels).set(tpm)
+
+ if rpm is not None:
+ _labels = prometheus_label_factory(
+ supported_enum_labels=self.get_labels_for_metric(
+ metric_name="litellm_deployment_rpm_limit"
+ ),
+ enum_values=UserAPIKeyLabelValues(
+ litellm_model_name=litellm_model_name,
+ model_id=model_id,
+ api_base=api_base,
+ api_provider=llm_provider,
+ ),
+ )
+ self.litellm_deployment_rpm_limit.labels(**_labels).set(rpm)
+
def set_llm_deployment_success_metrics(
self,
request_kwargs: dict,
@@ -1786,6 +2001,16 @@ class PrometheusLogger(CustomLogger):
_model_info = _metadata.get("model_info") or {}
model_id = _model_info.get("id", None)
+ if _model_info or _litellm_params:
+ self._set_deployment_tpm_rpm_limit_metrics(
+ model_info=_model_info,
+ litellm_params=_litellm_params,
+ litellm_model_name=litellm_model_name,
+ model_id=model_id,
+ api_base=api_base,
+ llm_provider=llm_provider,
+ )
+
remaining_requests: Optional[int] = None
remaining_tokens: Optional[int] = None
if additional_headers := standard_logging_payload["hidden_params"][
@@ -2263,7 +2488,10 @@ class PrometheusLogger(CustomLogger):
async def fetch_keys(
page_size: int, page: int
- ) -> Tuple[List[Union[str, UserAPIKeyAuth, LiteLLM_DeletedVerificationToken]], Optional[int]]:
+ ) -> Tuple[
+ List[Union[str, UserAPIKeyAuth, LiteLLM_DeletedVerificationToken]],
+ Optional[int],
+ ]:
key_list_response = await _list_key_helper(
prisma_client=prisma_client,
page=page,
@@ -2379,12 +2607,16 @@ class PrometheusLogger(CustomLogger):
# Get total user count
total_users = await prisma_client.db.litellm_usertable.count()
self.litellm_total_users_metric.set(total_users)
- verbose_logger.debug(f"Prometheus: set litellm_total_users to {total_users}")
+ verbose_logger.debug(
+ f"Prometheus: set litellm_total_users to {total_users}"
+ )
# Get total team count
total_teams = await prisma_client.db.litellm_teamtable.count()
self.litellm_teams_count_metric.set(total_teams)
- verbose_logger.debug(f"Prometheus: set litellm_teams_count to {total_teams}")
+ verbose_logger.debug(
+ f"Prometheus: set litellm_teams_count to {total_teams}"
+ )
except Exception as e:
verbose_logger.exception(
f"Error initializing user/team count metrics: {str(e)}"
@@ -2412,8 +2644,8 @@ class PrometheusLogger(CustomLogger):
self,
user_api_team: Optional[str],
user_api_team_alias: Optional[str],
- team_spend: float,
- team_max_budget: float,
+ team_spend: Optional[float],
+ team_max_budget: Optional[float],
response_cost: float,
):
"""
@@ -2575,7 +2807,7 @@ class PrometheusLogger(CustomLogger):
user_api_key: Optional[str],
user_api_key_alias: Optional[str],
response_cost: float,
- key_max_budget: float,
+ key_max_budget: Optional[float],
key_spend: Optional[float],
):
if user_api_key:
@@ -2592,7 +2824,7 @@ class PrometheusLogger(CustomLogger):
self,
user_api_key: str,
user_api_key_alias: str,
- key_max_budget: float,
+ key_max_budget: Optional[float],
key_spend: Optional[float],
response_cost: float,
) -> UserAPIKeyAuth:
@@ -2673,12 +2905,14 @@ class PrometheusLogger(CustomLogger):
max_budget=max_budget,
)
try:
+ # Note: Setting check_db_only=True bypasses cache and hits DB on every request,
+ # causing huge latency increase and CPU spikes. Keep check_db_only=False.
user_info = await get_user_object(
user_id=user_id,
prisma_client=prisma_client,
user_api_key_cache=user_api_key_cache,
user_id_upsert=False,
- check_db_only=True,
+ check_db_only=False,
)
except Exception as e:
verbose_logger.debug(
diff --git a/litellm/integrations/prometheus_services.py b/litellm/integrations/prometheus_services.py
index a5f2f0b5c72..55ce758ece6 100644
--- a/litellm/integrations/prometheus_services.py
+++ b/litellm/integrations/prometheus_services.py
@@ -105,6 +105,11 @@ class PrometheusServicesLogger:
return metrics
def is_metric_registered(self, metric_name) -> bool:
+ # Use _names_to_collectors (O(1)) instead of REGISTRY.collect() (O(n)) to avoid
+ # perf regression when a new Router is created per request (e.g. router_settings in DB).
+ names_to_collectors = getattr(self.REGISTRY, "_names_to_collectors", None)
+ if names_to_collectors is not None:
+ return metric_name in names_to_collectors
for metric in self.REGISTRY.collect():
if metric_name == metric.name:
return True
diff --git a/litellm/litellm_core_utils/core_helpers.py b/litellm/litellm_core_utils/core_helpers.py
index 9cb0a00d9fc..7c8e2ebeaff 100644
--- a/litellm/litellm_core_utils/core_helpers.py
+++ b/litellm/litellm_core_utils/core_helpers.py
@@ -94,8 +94,8 @@ def map_finish_reason(
return "length"
elif finish_reason == "tool_use": # anthropic
return "tool_calls"
- elif finish_reason == "content_filtered":
- return "content_filter"
+ elif finish_reason == "compaction":
+ return "length"
return finish_reason
@@ -351,9 +351,9 @@ def filter_exceptions_from_params(data: Any, max_depth: int = 20) -> Any:
# Skip callable objects (functions, methods, lambdas) but not classes (type objects)
if callable(data) and not isinstance(data, type):
return None
- # Skip known non-serializable object types (Logging, etc.)
+ # Skip known non-serializable object types (Logging, Router, etc.)
obj_type_name = type(data).__name__
- if obj_type_name in ["Logging", "LiteLLMLoggingObj"]:
+ if obj_type_name in ["Logging", "LiteLLMLoggingObj", "Router"]:
return None
if isinstance(data, dict):
diff --git a/litellm/litellm_core_utils/get_litellm_params.py b/litellm/litellm_core_utils/get_litellm_params.py
index e290101f8bf..36a8dfdb5a6 100644
--- a/litellm/litellm_core_utils/get_litellm_params.py
+++ b/litellm/litellm_core_utils/get_litellm_params.py
@@ -1,19 +1,48 @@
from typing import Optional
+# Pre-define optional kwargs keys as frozenset for O(1) lookups
+# These are extracted from kwargs only if present, avoiding unnecessary .get() calls
+_OPTIONAL_KWARGS_KEYS = frozenset({
+ "azure_ad_token",
+ "tenant_id",
+ "client_id",
+ "client_secret",
+ "azure_username",
+ "azure_password",
+ "azure_scope",
+ "timeout",
+ "bucket_name",
+ "vertex_credentials",
+ "vertex_project",
+ "vertex_location",
+ "vertex_ai_project",
+ "vertex_ai_location",
+ "vertex_ai_credentials",
+ "aws_region_name",
+ "aws_access_key_id",
+ "aws_secret_access_key",
+ "aws_session_token",
+ "aws_session_name",
+ "aws_profile_name",
+ "aws_role_name",
+ "aws_web_identity_token",
+ "aws_sts_endpoint",
+ "aws_external_id",
+ "aws_bedrock_runtime_endpoint",
+ "tpm",
+ "rpm",
+})
+
+
def _get_base_model_from_litellm_call_metadata(
metadata: Optional[dict],
) -> Optional[str]:
if metadata is None:
return None
-
- if metadata is not None:
- model_info = metadata.get("model_info", {})
-
- if model_info is not None:
- base_model = model_info.get("base_model", None)
- if base_model is not None:
- return base_model
+ model_info = metadata.get("model_info")
+ if model_info:
+ return model_info.get("base_model")
return None
@@ -66,6 +95,7 @@ def get_litellm_params(
litellm_request_debug: Optional[bool] = None,
**kwargs,
) -> dict:
+ # Build base dict with explicit parameters (always included)
litellm_params = {
"acompletion": acompletion,
"api_key": api_key,
@@ -93,8 +123,11 @@ def get_litellm_params(
"text_completion": text_completion,
"azure_ad_token_provider": azure_ad_token_provider,
"user_continue_message": user_continue_message,
- "base_model": base_model or (
- _get_base_model_from_litellm_call_metadata(metadata=metadata) if metadata else None
+ "base_model": base_model
+ or (
+ _get_base_model_from_litellm_call_metadata(metadata=metadata)
+ if metadata
+ else None
),
"litellm_trace_id": litellm_trace_id,
"litellm_session_id": litellm_session_id,
@@ -109,35 +142,15 @@ def get_litellm_params(
"ssl_verify": ssl_verify,
"merge_reasoning_content_in_choices": merge_reasoning_content_in_choices,
"api_version": api_version,
- "azure_ad_token": kwargs.get("azure_ad_token"),
- "tenant_id": kwargs.get("tenant_id"),
- "client_id": kwargs.get("client_id"),
- "client_secret": kwargs.get("client_secret"),
- "azure_username": kwargs.get("azure_username"),
- "azure_password": kwargs.get("azure_password"),
- "azure_scope": kwargs.get("azure_scope"),
"max_retries": max_retries,
- "timeout": kwargs.get("timeout"),
- "bucket_name": kwargs.get("bucket_name"),
- "vertex_credentials": kwargs.get("vertex_credentials"),
- "vertex_project": kwargs.get("vertex_project"),
- "vertex_location": kwargs.get("vertex_location"),
- "vertex_ai_project": kwargs.get("vertex_ai_project"),
- "vertex_ai_location": kwargs.get("vertex_ai_location"),
- "vertex_ai_credentials": kwargs.get("vertex_ai_credentials"),
"use_litellm_proxy": use_litellm_proxy,
"litellm_request_debug": litellm_request_debug,
- "aws_region_name": kwargs.get("aws_region_name"),
- # AWS credentials for Bedrock/Sagemaker
- "aws_access_key_id": kwargs.get("aws_access_key_id"),
- "aws_secret_access_key": kwargs.get("aws_secret_access_key"),
- "aws_session_token": kwargs.get("aws_session_token"),
- "aws_session_name": kwargs.get("aws_session_name"),
- "aws_profile_name": kwargs.get("aws_profile_name"),
- "aws_role_name": kwargs.get("aws_role_name"),
- "aws_web_identity_token": kwargs.get("aws_web_identity_token"),
- "aws_sts_endpoint": kwargs.get("aws_sts_endpoint"),
- "aws_external_id": kwargs.get("aws_external_id"),
- "aws_bedrock_runtime_endpoint": kwargs.get("aws_bedrock_runtime_endpoint"),
}
+
+ # Sparse extraction: only add kwargs keys that are actually present
+ if kwargs:
+ for key in _OPTIONAL_KWARGS_KEYS:
+ if key in kwargs:
+ litellm_params[key] = kwargs[key]
+
return litellm_params
diff --git a/litellm/litellm_core_utils/initialize_dynamic_callback_params.py b/litellm/litellm_core_utils/initialize_dynamic_callback_params.py
index c425319b4d4..ff521d47804 100644
--- a/litellm/litellm_core_utils/initialize_dynamic_callback_params.py
+++ b/litellm/litellm_core_utils/initialize_dynamic_callback_params.py
@@ -1,8 +1,35 @@
from typing import Dict, Optional
-
from litellm.secret_managers.main import get_secret_str
from litellm.types.utils import StandardCallbackDynamicParams
+# Hardcoded list of supported callback params to avoid runtime inspection issues with TypedDict
+_supported_callback_params = [
+ "langfuse_public_key",
+ "langfuse_secret",
+ "langfuse_secret_key",
+ "langfuse_host",
+ "langfuse_prompt_version",
+ "gcs_bucket_name",
+ "gcs_path_service_account",
+ "langsmith_api_key",
+ "langsmith_project",
+ "langsmith_base_url",
+ "langsmith_sampling_rate",
+ "langsmith_tenant_id",
+ "humanloop_api_key",
+ "arize_api_key",
+ "arize_space_key",
+ "arize_space_id",
+ "posthog_api_key",
+ "posthog_host",
+ "braintrust_api_key",
+ "braintrust_project",
+ "braintrust_host",
+ "slack_webhook_url",
+ "lunary_public_key",
+ "turn_off_message_logging",
+]
+
def initialize_standard_callback_dynamic_params(
kwargs: Optional[Dict] = None,
@@ -15,13 +42,10 @@ def initialize_standard_callback_dynamic_params(
standard_callback_dynamic_params = StandardCallbackDynamicParams()
if kwargs:
- _supported_callback_params = (
- StandardCallbackDynamicParams.__annotations__.keys()
- )
-
+ # 1. Check top-level kwargs
for param in _supported_callback_params:
if param in kwargs:
- _param_value = kwargs.pop(param)
+ _param_value = kwargs.get(param)
if (
_param_value is not None
and isinstance(_param_value, str)
@@ -30,4 +54,22 @@ def initialize_standard_callback_dynamic_params(
_param_value = get_secret_str(secret_name=_param_value)
standard_callback_dynamic_params[param] = _param_value # type: ignore
+ # 2. Fallback: check "metadata" or "litellm_params" -> "metadata"
+ metadata = (kwargs.get("metadata") or {}).copy()
+ litellm_params = kwargs.get("litellm_params") or {}
+ if isinstance(litellm_params, dict):
+ metadata.update(litellm_params.get("metadata") or {})
+
+ if isinstance(metadata, dict):
+ for param in _supported_callback_params:
+ if param not in standard_callback_dynamic_params and param in metadata:
+ _param_value = metadata.get(param)
+ if (
+ _param_value is not None
+ and isinstance(_param_value, str)
+ and "os.environ/" in _param_value
+ ):
+ _param_value = get_secret_str(secret_name=_param_value)
+ standard_callback_dynamic_params[param] = _param_value # type: ignore
+
return standard_callback_dynamic_params
diff --git a/litellm/litellm_core_utils/litellm_logging.py b/litellm/litellm_core_utils/litellm_logging.py
index dba22beb139..3b9ed1577a9 100644
--- a/litellm/litellm_core_utils/litellm_logging.py
+++ b/litellm/litellm_core_utils/litellm_logging.py
@@ -204,8 +204,17 @@ except Exception as e:
EnterpriseStandardLoggingPayloadSetupVAR = None
_in_memory_loggers: List[Any] = []
+_STANDARD_LOGGING_METADATA_KEYS: frozenset = frozenset(
+ StandardLoggingMetadata.__annotations__.keys()
+)
+
### GLOBAL VARIABLES ###
+# Cache custom pricing keys as frozenset for O(1) lookups instead of looping through 49 keys
+_CUSTOM_PRICING_KEYS: frozenset = frozenset(
+ CustomPricingLiteLLMParams.model_fields.keys()
+)
+
sentry_sdk_instance = None
capture_exception = None
add_breadcrumb = None
@@ -331,7 +340,9 @@ class Logging(LiteLLMLoggingBaseClass):
self.start_time = start_time # log the call start time
self.call_type = call_type
self.litellm_call_id = litellm_call_id
- self.litellm_trace_id: str = litellm_trace_id if litellm_trace_id else str(uuid.uuid4())
+ self.litellm_trace_id: str = (
+ litellm_trace_id if litellm_trace_id else str(uuid.uuid4())
+ )
self.function_id = function_id
self.streaming_chunks: List[Any] = [] # for generating complete stream response
self.sync_streaming_chunks: List[
@@ -540,10 +551,11 @@ class Logging(LiteLLMLoggingBaseClass):
if "stream_options" in additional_params:
self.stream_options = additional_params["stream_options"]
## check if custom pricing set ##
- custom_pricing_keys = CustomPricingLiteLLMParams.model_fields.keys()
- for key in custom_pricing_keys:
- if litellm_params.get(key) is not None:
- self.custom_pricing = True
+ if any(
+ litellm_params.get(key) is not None
+ for key in _CUSTOM_PRICING_KEYS & litellm_params.keys()
+ ):
+ self.custom_pricing = True
if "custom_llm_provider" in self.model_call_details:
self.custom_llm_provider = self.model_call_details["custom_llm_provider"]
@@ -1290,6 +1302,7 @@ class Logging(LiteLLMLoggingBaseClass):
output_cost: float,
total_cost: float,
cost_for_built_in_tools_cost_usd_dollar: float,
+ additional_costs: Optional[dict] = None,
original_cost: Optional[float] = None,
discount_percent: Optional[float] = None,
discount_amount: Optional[float] = None,
@@ -1305,6 +1318,7 @@ class Logging(LiteLLMLoggingBaseClass):
output_cost: Cost of output/completion tokens
cost_for_built_in_tools_cost_usd_dollar: Cost of built-in tools
total_cost: Total cost of request
+ additional_costs: Free-form additional costs dict (e.g., {"azure_model_router_flat_cost": 0.00014})
original_cost: Cost before discount
discount_percent: Discount percentage (0.05 = 5%)
discount_amount: Discount amount in USD
@@ -1320,6 +1334,10 @@ class Logging(LiteLLMLoggingBaseClass):
tool_usage_cost=cost_for_built_in_tools_cost_usd_dollar,
)
+ # Store additional costs if provided (free-form dict for extensibility)
+ if additional_costs and isinstance(additional_costs, dict) and len(additional_costs) > 0:
+ self.cost_breakdown["additional_costs"] = additional_costs
+
# Store discount information if provided
if original_cost is not None:
self.cost_breakdown["original_cost"] = original_cost
@@ -1631,11 +1649,19 @@ class Logging(LiteLLMLoggingBaseClass):
"standard_logging_object"
)
) is not None:
- standard_logging_payload["response"] = (
+ response_dict = (
result.model_dump()
if hasattr(result, "model_dump")
else dict(result)
)
+ # Ensure usage is properly included with transformed chat format
+ if transformed_usage is not None:
+ response_dict["usage"] = (
+ transformed_usage.model_dump()
+ if hasattr(transformed_usage, "model_dump")
+ else dict(transformed_usage)
+ )
+ standard_logging_payload["response"] = response_dict
elif isinstance(result, TranscriptionResponse):
from litellm.litellm_core_utils.llm_cost_calc.usage_object_transformation import (
TranscriptionUsageObjectTransformation,
@@ -2321,18 +2347,28 @@ class Logging(LiteLLMLoggingBaseClass):
batch_cost = kwargs.get("batch_cost", None)
batch_usage = kwargs.get("batch_usage", None)
batch_models = kwargs.get("batch_models", None)
- if all([batch_cost, batch_usage, batch_models]) is not None:
+ has_explicit_batch_data = all(
+ x is not None for x in (batch_cost, batch_usage, batch_models)
+ )
+
+ should_compute_batch_data = (
+ not is_base64_unified_file_id
+ or not has_explicit_batch_data
+ and result.status == "completed"
+ )
+ if has_explicit_batch_data:
result._hidden_params["response_cost"] = batch_cost
result._hidden_params["batch_models"] = batch_models
result.usage = batch_usage
- elif not is_base64_unified_file_id: # only run for non-unified file ids
+ elif should_compute_batch_data:
(
response_cost,
batch_usage,
batch_models,
) = await _handle_completed_batch(
- batch=result, custom_llm_provider=self.custom_llm_provider
+ batch=result,
+ custom_llm_provider=self.custom_llm_provider,
)
result._hidden_params["response_cost"] = response_cost
@@ -2404,6 +2440,36 @@ class Logging(LiteLLMLoggingBaseClass):
standard_built_in_tools_params=self.standard_built_in_tools_params,
)
+ # print standard logging payload
+ if (
+ standard_logging_payload := self.model_call_details.get(
+ "standard_logging_object"
+ )
+ ) is not None:
+ emit_standard_logging_payload(standard_logging_payload)
+ elif self.call_type == "pass_through_endpoint":
+ print_verbose(
+ "Async success callbacks: Got a pass-through endpoint response"
+ )
+
+ self.model_call_details["async_complete_streaming_response"] = result
+
+ # cost calculation not possible for pass-through
+ self.model_call_details["response_cost"] = None
+
+ ## STANDARDIZED LOGGING PAYLOAD
+ self.model_call_details[
+ "standard_logging_object"
+ ] = get_standard_logging_object_payload(
+ kwargs=self.model_call_details,
+ init_response_obj=result,
+ start_time=start_time,
+ end_time=end_time,
+ logging_obj=self,
+ status="success",
+ standard_built_in_tools_params=self.standard_built_in_tools_params,
+ )
+
# print standard logging payload
if (
standard_logging_payload := self.model_call_details.get(
@@ -3302,6 +3368,7 @@ def _get_masked_values(
"token",
"key",
"secret",
+ "vertex_credentials",
]
return {
k: (
@@ -3860,18 +3927,6 @@ def _init_custom_logger_compatible_class( # noqa: PLR0915
return langfuse_logger # type: ignore
elif logging_integration == "langfuse_otel":
from litellm.integrations.langfuse.langfuse_otel import LangfuseOtelLogger
- from litellm.integrations.opentelemetry import (
- OpenTelemetry,
- OpenTelemetryConfig,
- )
-
- langfuse_otel_config = LangfuseOtelLogger.get_langfuse_otel_config()
-
- # The endpoint and headers are now set as environment variables by get_langfuse_otel_config()
- otel_config = OpenTelemetryConfig(
- exporter=langfuse_otel_config.protocol,
- headers=langfuse_otel_config.otlp_auth_headers,
- )
for callback in _in_memory_loggers:
if (
@@ -3879,8 +3934,10 @@ def _init_custom_logger_compatible_class( # noqa: PLR0915
and callback.callback_name == "langfuse_otel"
):
return callback # type: ignore
+ # Allow LangfuseOtelLogger to initialize its own config safely
+ # This prevents startup crashes if LANGFUSE keys are not in env (e.g. for dynamic usage)
_otel_logger = LangfuseOtelLogger(
- config=otel_config, callback_name="langfuse_otel"
+ config=None, callback_name="langfuse_otel"
)
_in_memory_loggers.append(_otel_logger)
return _otel_logger # type: ignore
@@ -4254,15 +4311,21 @@ def use_custom_pricing_for_model(litellm_params: Optional[dict]) -> bool:
if litellm_params is None:
return False
+ # Check litellm_params using set intersection (only check keys that exist in both)
+ matching_keys = _CUSTOM_PRICING_KEYS & litellm_params.keys()
+ for key in matching_keys:
+ if litellm_params.get(key) is not None:
+ return True
+
+ # Check model_info
metadata: dict = litellm_params.get("metadata", {}) or {}
model_info: dict = metadata.get("model_info", {}) or {}
- custom_pricing_keys = CustomPricingLiteLLMParams.model_fields.keys()
- for key in custom_pricing_keys:
- if litellm_params.get(key, None) is not None:
- return True
- elif model_info.get(key, None) is not None:
- return True
+ if model_info:
+ matching_keys = _CUSTOM_PRICING_KEYS & model_info.keys()
+ for key in matching_keys:
+ if model_info.get(key) is not None:
+ return True
return False
@@ -4450,6 +4513,7 @@ class StandardLoggingPayloadSetup:
user_api_key_request_route=None,
spend_logs_metadata=None,
requester_ip_address=None,
+ user_agent=None,
requester_metadata=None,
prompt_management_metadata=prompt_management_metadata,
applied_guardrails=applied_guardrails,
@@ -4461,17 +4525,12 @@ class StandardLoggingPayloadSetup:
user_api_key_auth_metadata=None,
)
if isinstance(metadata, dict):
- # Filter the metadata dictionary to include only the specified keys
- supported_keys = StandardLoggingMetadata.__annotations__.keys()
- for key in supported_keys:
- if key in metadata:
- clean_metadata[key] = metadata[key] # type: ignore
+ for key in metadata.keys() & _STANDARD_LOGGING_METADATA_KEYS:
+ clean_metadata[key] = metadata[key] # type: ignore
- if metadata.get("user_api_key") is not None:
- if is_valid_sha256_hash(str(metadata.get("user_api_key"))):
- clean_metadata["user_api_key_hash"] = metadata.get(
- "user_api_key"
- ) # this is the hash
+ user_api_key = metadata.get("user_api_key")
+ if user_api_key and isinstance(user_api_key, str) and is_valid_sha256_hash(user_api_key):
+ clean_metadata["user_api_key_hash"] = user_api_key
_potential_requester_metadata = metadata.get(
"metadata", None
) # check if user passed metadata in the sdk request - e.g. metadata for langsmith logging - https://docs.litellm.ai/docs/observability/langsmith_integration#set-langsmith-fields
@@ -4530,6 +4589,10 @@ class StandardLoggingPayloadSetup:
)
elif isinstance(usage, Usage):
return usage
+ elif isinstance(usage, ResponseAPIUsage):
+ return ResponseAPILoggingUtils._transform_response_api_usage_to_chat_usage(
+ usage
+ )
elif isinstance(usage, dict):
if ResponseAPILoggingUtils._is_response_api_usage(usage):
return (
@@ -4658,7 +4721,10 @@ class StandardLoggingPayloadSetup:
@staticmethod
def strip_trailing_slash(api_base: Optional[str]) -> Optional[str]:
if api_base:
- return api_base.rstrip("/")
+ if api_base.endswith("//"):
+ return api_base.rstrip("/")
+ if api_base[-1] == "/":
+ return api_base[:-1]
return api_base
@staticmethod
@@ -4727,7 +4793,14 @@ class StandardLoggingPayloadSetup:
) -> StandardLoggingPayloadErrorInformation:
from litellm.constants import MAXIMUM_TRACEBACK_LINES_TO_LOG
- error_status: str = str(getattr(original_exception, "status_code", ""))
+ # Check for 'code' first (used by ProxyException), then fall back to 'status_code' (used by LiteLLM exceptions)
+ # Ensure error_code is always a string for Prisma Python JSON field compatibility
+ error_code_attr = getattr(original_exception, "code", None)
+ if error_code_attr is not None and str(error_code_attr) not in ("", "None"):
+ error_status: str = str(error_code_attr)
+ else:
+ status_code_attr = getattr(original_exception, "status_code", None)
+ error_status = str(status_code_attr) if status_code_attr is not None else ""
error_class: str = (
str(original_exception.__class__.__name__) if original_exception else ""
)
@@ -5132,6 +5205,7 @@ def get_standard_logging_object_payload(
model_group=_model_group,
model_id=_model_id,
requester_ip_address=clean_metadata.get("requester_ip_address", None),
+ user_agent=clean_metadata.get("user_agent", None),
messages=StandardLoggingPayloadSetup.append_system_prompt_messages(
kwargs=kwargs, messages=kwargs.get("messages")
),
@@ -5197,6 +5271,7 @@ def get_standard_logging_metadata(
user_api_key_team_alias=None,
spend_logs_metadata=None,
requester_ip_address=None,
+ user_agent=None,
requester_metadata=None,
user_api_key_end_user_id=None,
prompt_management_metadata=None,
diff --git a/litellm/litellm_core_utils/llm_cost_calc/utils.py b/litellm/litellm_core_utils/llm_cost_calc/utils.py
index 785976ed319..2308dc7beca 100644
--- a/litellm/litellm_core_utils/llm_cost_calc/utils.py
+++ b/litellm/litellm_core_utils/llm_cost_calc/utils.py
@@ -23,6 +23,15 @@ def _is_above_128k(tokens: float) -> bool:
return False
+def get_billable_input_tokens(usage: Usage) -> int:
+ """
+ Returns the number of billable input tokens.
+ Subtracts cached tokens from prompt tokens if applicable.
+ """
+ details = _parse_prompt_tokens_details(usage)
+ return usage.prompt_tokens - details["cache_hit_tokens"]
+
+
def select_cost_metric_for_model(
model_info: ModelInfo,
) -> Literal["cost_per_character", "cost_per_token"]:
@@ -190,7 +199,6 @@ def _get_token_base_cost(
1000 if "k" in threshold_str else 1
)
if usage.prompt_tokens > threshold:
-
prompt_base_cost = cast(
float, _get_cost_per_unit(model_info, key, prompt_base_cost)
)
@@ -207,6 +215,9 @@ def _get_token_base_cost(
cache_creation_tiered_key = (
f"cache_creation_input_token_cost_above_{threshold_str}_tokens"
)
+ cache_creation_1hr_tiered_key = (
+ f"cache_creation_input_token_cost_above_1hr_above_{threshold_str}_tokens"
+ )
cache_read_tiered_key = (
f"cache_read_input_token_cost_above_{threshold_str}_tokens"
)
@@ -221,6 +232,16 @@ def _get_token_base_cost(
),
)
+ if cache_creation_1hr_tiered_key in model_info:
+ cache_creation_cost_above_1hr = cast(
+ float,
+ _get_cost_per_unit(
+ model_info,
+ cache_creation_1hr_tiered_key,
+ cache_creation_cost_above_1hr,
+ ),
+ )
+
if cache_read_tiered_key in model_info:
cache_read_cost = cast(
float,
@@ -566,14 +587,28 @@ def generic_cost_per_token( # noqa: PLR0915
if usage.prompt_tokens_details:
prompt_tokens_details = _parse_prompt_tokens_details(usage)
- ## EDGE CASE - text tokens not set inside PromptTokensDetails
+ ## EDGE CASE - text tokens not set or includes cached tokens (double-counting)
+ ## Some providers (like xAI) report text_tokens = prompt_tokens (including cached)
+ ## We detect this when: text_tokens + cached_tokens + other > prompt_tokens
+ ## Ref: https://github.com/BerriAI/litellm/issues/19680, #14874, #14875
- if prompt_tokens_details["text_tokens"] == 0:
+ cache_hit = prompt_tokens_details["cache_hit_tokens"]
+ text_tokens = prompt_tokens_details["text_tokens"]
+ audio_tokens = prompt_tokens_details["audio_tokens"]
+ cache_creation = prompt_tokens_details["cache_creation_tokens"]
+ image_tokens = prompt_tokens_details["image_tokens"]
+
+ # Check for double-counting: sum of details > prompt_tokens means overlap
+ total_details = text_tokens + cache_hit + audio_tokens + cache_creation + image_tokens
+ has_double_counting = cache_hit > 0 and total_details > usage.prompt_tokens
+
+ if text_tokens == 0 or has_double_counting:
text_tokens = (
usage.prompt_tokens
- - prompt_tokens_details["cache_hit_tokens"]
- - prompt_tokens_details["audio_tokens"]
- - prompt_tokens_details["cache_creation_tokens"]
+ - cache_hit
+ - audio_tokens
+ - cache_creation
+ - image_tokens
)
prompt_tokens_details["text_tokens"] = text_tokens
@@ -619,7 +654,11 @@ def generic_cost_per_token( # noqa: PLR0915
# Calculate text tokens as remainder when we have a breakdown
# This handles cases like OpenAI's reasoning models where text_tokens isn't provided
text_tokens = max(
- 0, usage.completion_tokens - reasoning_tokens - audio_tokens - image_tokens
+ 0,
+ usage.completion_tokens
+ - reasoning_tokens
+ - audio_tokens
+ - image_tokens,
)
else:
# No breakdown at all, all tokens are text tokens
diff --git a/litellm/litellm_core_utils/llm_response_utils/convert_dict_to_response.py b/litellm/litellm_core_utils/llm_response_utils/convert_dict_to_response.py
index bbe28e3ec2c..25ad0a570cb 100644
--- a/litellm/litellm_core_utils/llm_response_utils/convert_dict_to_response.py
+++ b/litellm/litellm_core_utils/llm_response_utils/convert_dict_to_response.py
@@ -21,11 +21,13 @@ from litellm.types.utils import (
ChatCompletionMessageToolCall,
ChatCompletionRedactedThinkingBlock,
Choices,
+ CompletionTokensDetailsWrapper,
Delta,
EmbeddingResponse,
Function,
HiddenParams,
ImageResponse,
+ PromptTokensDetailsWrapper,
)
from litellm.types.utils import Logprobs as TextCompletionLogprobs
from litellm.types.utils import (
@@ -304,6 +306,22 @@ class LiteLLMResponseObjectHandler:
"text_tokens": 0,
}
+ # Map Responses API naming to Chat Completions API naming for cost calculator
+ if usage.get("prompt_tokens") is None:
+ usage["prompt_tokens"] = usage.get("input_tokens", 0)
+ if usage.get("completion_tokens") is None:
+ usage["completion_tokens"] = usage.get("output_tokens", 0)
+
+ # Convert dicts to wrapper objects so getattr() works in cost calculation
+ if isinstance(usage.get("input_tokens_details"), dict):
+ usage["prompt_tokens_details"] = PromptTokensDetailsWrapper(
+ **usage["input_tokens_details"]
+ )
+ if isinstance(usage.get("output_tokens_details"), dict):
+ usage["completion_tokens_details"] = CompletionTokensDetailsWrapper(
+ **usage["output_tokens_details"]
+ )
+
if model_response_object is None:
model_response_object = ImageResponse(**response_object)
return model_response_object
diff --git a/litellm/litellm_core_utils/logging_callback_manager.py b/litellm/litellm_core_utils/logging_callback_manager.py
index 4f76a5bad03..435ae078a65 100644
--- a/litellm/litellm_core_utils/logging_callback_manager.py
+++ b/litellm/litellm_core_utils/logging_callback_manager.py
@@ -114,6 +114,27 @@ class LoggingCallbackManager:
for c in remove_list:
callback_list.remove(c)
+ def remove_callbacks_by_type(self, callback_list, callback_type):
+ """
+ Remove all callbacks of a specific type from a callback list.
+
+ Args:
+ callback_list: The list to remove callbacks from (e.g., litellm.callbacks)
+ callback_type: The class type to match (e.g., SemanticToolFilterHook)
+
+ Example:
+ litellm.logging_callback_manager.remove_callbacks_by_type(
+ litellm.callbacks, SemanticToolFilterHook
+ )
+ """
+ if not isinstance(callback_list, list):
+ return
+
+ remove_list = [c for c in callback_list if isinstance(c, callback_type)]
+
+ for c in remove_list:
+ callback_list.remove(c)
+
def _add_string_callback_to_list(
self, callback: str, parent_list: List[Union[CustomLogger, Callable, str]]
):
diff --git a/litellm/litellm_core_utils/logging_worker.py b/litellm/litellm_core_utils/logging_worker.py
index 13a83956edd..d5eca9eeb55 100644
--- a/litellm/litellm_core_utils/logging_worker.py
+++ b/litellm/litellm_core_utils/logging_worker.py
@@ -415,6 +415,28 @@ class LoggingWorker:
"""
Safely log a message during shutdown, suppressing errors if logging is closed.
"""
+ # Check if logger has valid handlers before attempting to log
+ # During shutdown, handlers may be closed, causing ValueError when writing
+ if not hasattr(verbose_logger, 'handlers') or not verbose_logger.handlers:
+ return
+
+ # Check if any handler has a valid stream
+ has_valid_handler = False
+ for handler in verbose_logger.handlers:
+ try:
+ if hasattr(handler, 'stream') and handler.stream and not handler.stream.closed:
+ has_valid_handler = True
+ break
+ elif not hasattr(handler, 'stream'):
+ # Non-stream handlers (like NullHandler) are always valid
+ has_valid_handler = True
+ break
+ except (AttributeError, ValueError):
+ continue
+
+ if not has_valid_handler:
+ return
+
try:
if level == "debug":
verbose_logger.debug(message)
diff --git a/litellm/litellm_core_utils/model_param_helper.py b/litellm/litellm_core_utils/model_param_helper.py
index 91f2f1341cf..4d45c47c224 100644
--- a/litellm/litellm_core_utils/model_param_helper.py
+++ b/litellm/litellm_core_utils/model_param_helper.py
@@ -17,15 +17,16 @@ from litellm.types.rerank import RerankRequest
class ModelParamHelper:
+ # Cached at class level — deterministic set built from static OpenAI type annotations
+ _relevant_logging_args: frozenset = frozenset()
+
@staticmethod
def get_standard_logging_model_parameters(
model_parameters: dict,
) -> dict:
""" """
standard_logging_model_parameters: dict = {}
- supported_model_parameters = (
- ModelParamHelper._get_relevant_args_to_use_for_logging()
- )
+ supported_model_parameters = ModelParamHelper._relevant_logging_args
for key, value in model_parameters.items():
if key in supported_model_parameters:
@@ -172,3 +173,8 @@ class ModelParamHelper:
Get the kwargs to exclude from the cache key
"""
return set(["metadata"])
+
+
+ModelParamHelper._relevant_logging_args = frozenset(
+ ModelParamHelper._get_relevant_args_to_use_for_logging()
+)
diff --git a/litellm/litellm_core_utils/prompt_templates/common_utils.py b/litellm/litellm_core_utils/prompt_templates/common_utils.py
index 7790fb83361..b1c2d0a52f5 100644
--- a/litellm/litellm_core_utils/prompt_templates/common_utils.py
+++ b/litellm/litellm_core_utils/prompt_templates/common_utils.py
@@ -443,13 +443,21 @@ def update_messages_with_model_file_ids(
def update_responses_input_with_model_file_ids(
input: Any,
+ model_id: Optional[str] = None,
+ model_file_id_mapping: Optional[Dict[str, Dict[str, str]]] = None,
) -> Union[str, List[Dict[str, Any]]]:
"""
Updates responses API input with provider-specific file IDs.
File IDs are always inside the content array, not as direct input_file items.
- For managed files (unified file IDs), decodes the base64-encoded unified file ID
- and extracts the llm_output_file_id directly.
+ For managed files (unified file IDs), uses model_file_id_mapping if provided,
+ otherwise decodes the base64-encoded unified file ID and extracts the llm_output_file_id directly.
+
+ Args:
+ input: The responses API input parameter
+ model_id: The model ID to use for looking up provider-specific file IDs
+ model_file_id_mapping: Dictionary mapping litellm file IDs to provider file IDs
+ Format: {"litellm_file_id": {"model_id": "provider_file_id"}}
"""
from litellm.proxy.openai_files_endpoints.common_utils import (
_is_base64_encoded_unified_file_id,
@@ -479,22 +487,35 @@ def update_responses_input_with_model_file_ids(
):
file_id = content_item.get("file_id")
if file_id:
- # Check if this is a managed file ID (base64-encoded unified file ID)
- is_unified_file_id = _is_base64_encoded_unified_file_id(file_id)
- if is_unified_file_id:
- unified_file_id = convert_b64_uid_to_unified_uid(file_id)
- if "llm_output_file_id," in unified_file_id:
- provider_file_id = unified_file_id.split(
- "llm_output_file_id,"
- )[1].split(";")[0]
- else:
- # Fallback: keep original if we can't extract
- provider_file_id = file_id
+ provider_file_id = file_id # Default to original
+
+ # Check if we have a mapping for this file ID
+ if model_file_id_mapping and model_id and file_id in model_file_id_mapping:
+ # Use the model-specific file ID from mapping
+ provider_file_id = (
+ model_file_id_mapping.get(file_id, {}).get(model_id)
+ or file_id
+ )
updated_content_item = content_item.copy()
updated_content_item["file_id"] = provider_file_id
updated_content.append(updated_content_item)
else:
- updated_content.append(content_item)
+ # Check if this is a base64-encoded unified file ID without mapping
+ is_unified_file_id = _is_base64_encoded_unified_file_id(file_id)
+ if is_unified_file_id:
+ # Fallback: decode unified file ID
+ unified_file_id = convert_b64_uid_to_unified_uid(file_id)
+ if "llm_output_file_id," in unified_file_id:
+ provider_file_id = unified_file_id.split(
+ "llm_output_file_id,"
+ )[1].split(";")[0]
+
+ updated_content_item = content_item.copy()
+ updated_content_item["file_id"] = provider_file_id
+ updated_content.append(updated_content_item)
+ else:
+ # Not a managed file, keep as-is
+ updated_content.append(content_item)
else:
updated_content.append(content_item)
else:
@@ -506,6 +527,68 @@ def update_responses_input_with_model_file_ids(
return updated_input
+def update_responses_tools_with_model_file_ids(
+ tools: Optional[List[Dict[str, Any]]],
+ model_id: Optional[str] = None,
+ model_file_id_mapping: Optional[Dict[str, Dict[str, str]]] = None,
+) -> Optional[List[Dict[str, Any]]]:
+ """
+ Updates responses API tools with provider-specific file IDs.
+
+ Handles code_interpreter tools with container.file_ids.
+
+ Args:
+ tools: The responses API tools parameter
+ model_id: The model ID to use for looking up provider-specific file IDs
+ model_file_id_mapping: Dictionary mapping litellm file IDs to provider file IDs
+ Format: {"litellm_file_id": {"model_id": "provider_file_id"}}
+ """
+ if not tools or not isinstance(tools, list):
+ return tools
+
+ if not model_file_id_mapping or not model_id:
+ return tools
+
+ updated_tools = []
+ for tool in tools:
+ if not isinstance(tool, dict):
+ updated_tools.append(tool)
+ continue
+
+ updated_tool = tool.copy()
+
+ # Handle code_interpreter with container file_ids
+ if tool.get("type") == "code_interpreter":
+ container = tool.get("container")
+ if isinstance(container, dict):
+ container_file_ids = container.get("file_ids")
+ if isinstance(container_file_ids, list):
+ updated_file_ids = []
+ for file_id in container_file_ids:
+ if isinstance(file_id, str):
+ # Check if we have a mapping for this file ID
+ if file_id in model_file_id_mapping:
+ # Map to provider-specific file ID
+ provider_file_id = (
+ model_file_id_mapping.get(file_id, {}).get(model_id)
+ or file_id
+ )
+ updated_file_ids.append(provider_file_id)
+ else:
+ updated_file_ids.append(file_id)
+ else:
+ updated_file_ids.append(file_id)
+
+ # Update the tool with new file IDs
+ updated_container = container.copy()
+ updated_container["file_ids"] = updated_file_ids
+ updated_tool["container"] = updated_container
+
+ updated_tools.append(updated_tool)
+
+ return updated_tools
+
+
def extract_file_data(file_data: FileTypes) -> ExtractedFileData:
"""
Extracts and processes file data from various input formats.
diff --git a/litellm/litellm_core_utils/prompt_templates/factory.py b/litellm/litellm_core_utils/prompt_templates/factory.py
index 30263543fc6..f9ecd78ff1c 100644
--- a/litellm/litellm_core_utils/prompt_templates/factory.py
+++ b/litellm/litellm_core_utils/prompt_templates/factory.py
@@ -1632,6 +1632,7 @@ def _sanitize_anthropic_tool_use_id(tool_use_id: str) -> str:
def convert_to_anthropic_tool_result(
message: Union[ChatCompletionToolMessage, ChatCompletionFunctionMessage],
+ force_base64: bool = False,
) -> AnthropicMessagesToolResultParam:
"""
OpenAI message with a tool result looks like:
@@ -1677,13 +1678,16 @@ def convert_to_anthropic_tool_result(
] = []
for content in content_list:
if content["type"] == "text":
- anthropic_content_list.append(
- AnthropicMessagesToolResultContent(
- type="text",
- text=content["text"],
- cache_control=content.get("cache_control", None),
- )
- )
+ # Only include cache_control if explicitly set and not None
+ # to avoid sending "cache_control": null which breaks some API channels
+ text_content: AnthropicMessagesToolResultContent = {
+ "type": "text",
+ "text": content["text"],
+ }
+ cache_control_value = content.get("cache_control")
+ if cache_control_value is not None:
+ text_content["cache_control"] = cache_control_value
+ anthropic_content_list.append(text_content)
elif content["type"] == "image_url":
format = (
content["image_url"].get("format")
@@ -1691,7 +1695,7 @@ def convert_to_anthropic_tool_result(
else None
)
_anthropic_image_param = create_anthropic_image_param(
- content["image_url"], format=format
+ content["image_url"], format=format, is_bedrock_invoke=force_base64
)
_anthropic_image_param = add_cache_control_to_content(
anthropic_content_element=_anthropic_image_param,
@@ -2053,6 +2057,12 @@ def anthropic_messages_pt( # noqa: PLR0915
else:
messages.append(DEFAULT_USER_CONTINUE_MESSAGE_TYPED)
+ # Bedrock invoke models have format: invoke/...
+ # Vertex AI Anthropic also doesn't support URL sources for images
+ is_bedrock_invoke = model.lower().startswith("invoke/")
+ is_vertex_ai = llm_provider.startswith("vertex_ai") if llm_provider else False
+ force_base64 = is_bedrock_invoke or is_vertex_ai
+
msg_i = 0
while msg_i < len(messages):
user_content: List[AnthropicMessagesUserMessageValues] = []
@@ -2162,7 +2172,9 @@ def anthropic_messages_pt( # noqa: PLR0915
):
# OpenAI's tool message content will always be a string
user_content.append(
- convert_to_anthropic_tool_result(user_message_types_block)
+ convert_to_anthropic_tool_result(
+ user_message_types_block, force_base64=force_base64
+ )
)
msg_i += 1
@@ -2178,6 +2190,16 @@ def anthropic_messages_pt( # noqa: PLR0915
while msg_i < len(messages) and messages[msg_i]["role"] == "assistant":
assistant_content_block: ChatCompletionAssistantMessage = messages[msg_i] # type: ignore
+ # Extract compaction_blocks from provider_specific_fields and add them first
+ _provider_specific_fields_raw = assistant_content_block.get(
+ "provider_specific_fields"
+ )
+ if isinstance(_provider_specific_fields_raw, dict):
+ _compaction_blocks = _provider_specific_fields_raw.get("compaction_blocks")
+ if _compaction_blocks and isinstance(_compaction_blocks, list):
+ # Add compaction blocks at the beginning of assistant content : https://platform.claude.com/docs/en/build-with-claude/compaction
+ assistant_content.extend(_compaction_blocks) # type: ignore
+
thinking_blocks = assistant_content_block.get("thinking_blocks", None)
if (
thinking_blocks is not None
@@ -3387,6 +3409,59 @@ def _convert_to_bedrock_tool_call_result(
return content_block
+def _deduplicate_bedrock_content_blocks(
+ blocks: List[BedrockContentBlock],
+ block_key: str,
+ id_key: str = "toolUseId",
+) -> List[BedrockContentBlock]:
+ """
+ Remove duplicate content blocks that share the same ID under ``block_key``.
+
+ Bedrock requires all toolResult and toolUse IDs within a single message to
+ be unique. When merging consecutive messages, duplicates can occur if the
+ same tool_call_id appears multiple times in conversation history.
+
+ When duplicates exist, the first occurrence is retained and subsequent ones
+ are discarded. A warning is logged for every dropped block so that
+ upstream duplication bugs remain visible.
+
+ Blocks that do not contain ``block_key`` (e.g., cachePoint, text) are
+ always preserved.
+
+ Args:
+ blocks: The list of Bedrock content blocks to deduplicate.
+ block_key: The dict key to inspect (e.g. ``"toolResult"`` or ``"toolUse"``).
+ id_key: The nested key that holds the unique ID (default ``"toolUseId"``).
+ """
+ seen_ids: Set[str] = set()
+ deduplicated: List[BedrockContentBlock] = []
+ for block in blocks:
+ keyed = block.get(block_key)
+ if keyed is not None and isinstance(keyed, dict):
+ block_id = keyed.get(id_key)
+ if block_id:
+ if block_id in seen_ids:
+ verbose_logger.warning(
+ "Bedrock Converse: dropping duplicate %s block with "
+ "%s=%s. This may indicate duplicate tool messages in "
+ "conversation history.",
+ block_key,
+ id_key,
+ block_id,
+ )
+ continue
+ seen_ids.add(block_id)
+ deduplicated.append(block)
+ return deduplicated
+
+
+def _deduplicate_bedrock_tool_content(
+ tool_content: List[BedrockContentBlock],
+) -> List[BedrockContentBlock]:
+ """Convenience wrapper: deduplicate ``toolResult`` blocks by ``toolUseId``."""
+ return _deduplicate_bedrock_content_blocks(tool_content, "toolResult")
+
+
def _insert_assistant_continue_message(
messages: List[BedrockMessageBlock],
assistant_continue_message: Optional[
@@ -3855,6 +3930,8 @@ class BedrockConverseMessagesProcessor:
tool_content.append(cache_point_block)
msg_i += 1
+ # Deduplicate toolResult blocks with the same toolUseId
+ tool_content = _deduplicate_bedrock_tool_content(tool_content)
if tool_content:
# if last message was a 'user' message, then add a blank assistant message (bedrock requires alternating roles)
if len(contents) > 0 and contents[-1]["role"] == "user":
@@ -3920,10 +3997,12 @@ class BedrockConverseMessagesProcessor:
assistant_parts=assistants_parts,
)
elif element["type"] == "text":
- assistants_part = BedrockContentBlock(
- text=element["text"]
- )
- assistants_parts.append(assistants_part)
+ # Skip completely empty strings to avoid blank content blocks
+ if element.get("text", "").strip():
+ assistants_part = BedrockContentBlock(
+ text=element["text"]
+ )
+ assistants_parts.append(assistants_part)
elif element["type"] == "image_url":
if isinstance(element["image_url"], dict):
image_url = element["image_url"]["url"]
@@ -3948,9 +4027,12 @@ class BedrockConverseMessagesProcessor:
elif _assistant_content is not None and isinstance(
_assistant_content, str
):
- assistant_content.append(
- BedrockContentBlock(text=_assistant_content)
- )
+ # Skip completely empty strings to avoid blank content blocks
+ if _assistant_content.strip():
+ assistant_content.append(
+ BedrockContentBlock(text=_assistant_content)
+ )
+ # If content is empty/whitespace, skip it (don't add a placeholder)
# Add cache point block for assistant string content
_cache_point_block = (
litellm.AmazonConverseConfig()._get_cache_point_block(
@@ -3968,6 +4050,8 @@ class BedrockConverseMessagesProcessor:
msg_i += 1
+ assistant_content = _deduplicate_bedrock_content_blocks(assistant_content, "toolUse")
+
if assistant_content:
contents.append(
BedrockMessageBlock(role="assistant", content=assistant_content)
@@ -4218,6 +4302,8 @@ def _bedrock_converse_messages_pt( # noqa: PLR0915
tool_content.append(cache_point_block)
msg_i += 1
+ # Deduplicate toolResult blocks with the same toolUseId
+ tool_content = _deduplicate_bedrock_tool_content(tool_content)
if tool_content:
# if last message was a 'user' message, then add a blank assistant message (bedrock requires alternating roles)
if len(contents) > 0 and contents[-1]["role"] == "user":
@@ -4277,12 +4363,11 @@ def _bedrock_converse_messages_pt( # noqa: PLR0915
assistant_parts=assistants_parts,
)
elif element["type"] == "text":
- # AWS Bedrock doesn't allow empty or whitespace-only text content, so use placeholder for empty strings
- text_content = (
- element["text"] if element["text"].strip() else "."
- )
- assistants_part = BedrockContentBlock(text=text_content)
- assistants_parts.append(assistants_part)
+ # AWS Bedrock doesn't allow empty or whitespace-only text content
+ # Skip completely empty strings to avoid blank content blocks
+ if element.get("text", "").strip():
+ assistants_part = BedrockContentBlock(text=element["text"])
+ assistants_parts.append(assistants_part)
elif element["type"] == "image_url":
if isinstance(element["image_url"], dict):
image_url = element["image_url"]["url"]
@@ -4305,9 +4390,9 @@ def _bedrock_converse_messages_pt( # noqa: PLR0915
assistants_parts.append(_cache_point_block)
assistant_content.extend(assistants_parts)
elif _assistant_content is not None and isinstance(_assistant_content, str):
- # AWS Bedrock doesn't allow empty or whitespace-only text content, so use placeholder for empty strings
- text_content = _assistant_content if _assistant_content.strip() else "."
- assistant_content.append(BedrockContentBlock(text=text_content))
+ # Skip completely empty strings to avoid blank content blocks
+ if _assistant_content.strip():
+ assistant_content.append(BedrockContentBlock(text=_assistant_content))
# Add cache point block for assistant string content
_cache_point_block = (
litellm.AmazonConverseConfig()._get_cache_point_block(
@@ -4324,6 +4409,8 @@ def _bedrock_converse_messages_pt( # noqa: PLR0915
msg_i += 1
+ assistant_content = _deduplicate_bedrock_content_blocks(assistant_content, "toolUse")
+
if assistant_content:
contents.append(
BedrockMessageBlock(role="assistant", content=assistant_content)
@@ -4383,6 +4470,32 @@ def add_cache_point_tool_block(tool: dict) -> Optional[BedrockToolBlock]:
return None
+def _is_bedrock_tool_block(tool: dict) -> bool:
+ """
+ Check if a tool is already a BedrockToolBlock.
+
+ BedrockToolBlock has one of: systemTool, toolSpec, or cachePoint.
+ This is used to detect tools that are already in Bedrock format
+ (e.g., systemTool for Nova grounding) vs OpenAI-style function tools
+ that need transformation.
+
+ Args:
+ tool: The tool dict to check
+
+ Returns:
+ True if the tool is already a BedrockToolBlock, False otherwise
+
+ Examples:
+ >>> _is_bedrock_tool_block({"systemTool": {"name": "nova_grounding"}})
+ True
+ >>> _is_bedrock_tool_block({"type": "function", "function": {...}})
+ False
+ """
+ return isinstance(tool, dict) and (
+ "systemTool" in tool or "toolSpec" in tool or "cachePoint" in tool
+ )
+
+
def _bedrock_tools_pt(tools: List) -> List[BedrockToolBlock]:
"""
OpenAI tools looks like:
@@ -4408,7 +4521,7 @@ def _bedrock_tools_pt(tools: List) -> List[BedrockToolBlock]:
]
"""
"""
- Bedrock toolConfig looks like:
+ Bedrock toolConfig looks like:
"tools": [
{
"toolSpec": {
@@ -4436,6 +4549,13 @@ def _bedrock_tools_pt(tools: List) -> List[BedrockToolBlock]:
tool_block_list: List[BedrockToolBlock] = []
for tool in tools:
+ # Check if tool is already a BedrockToolBlock (e.g., systemTool for Nova grounding)
+ if _is_bedrock_tool_block(tool):
+ # Already a BedrockToolBlock, pass it through
+ tool_block_list.append(tool) # type: ignore
+ continue
+
+ # Handle regular OpenAI-style function tools
parameters = tool.get("function", {}).get(
"parameters", {"type": "object", "properties": {}}
)
diff --git a/litellm/litellm_core_utils/prompt_templates/image_handling.py b/litellm/litellm_core_utils/prompt_templates/image_handling.py
index 5d0bedb776d..7137a4e4222 100644
--- a/litellm/litellm_core_utils/prompt_templates/image_handling.py
+++ b/litellm/litellm_core_utils/prompt_templates/image_handling.py
@@ -31,15 +31,19 @@ def _process_image_response(response: Response, url: str) -> str:
f"Error: Image size ({size_mb:.2f}MB) exceeds maximum allowed size ({MAX_IMAGE_URL_DOWNLOAD_SIZE_MB}MB). url={url}"
)
- image_bytes = response.content
+ # Stream download with size checking to prevent downloading huge files
+ max_bytes = int(MAX_IMAGE_URL_DOWNLOAD_SIZE_MB * 1024 * 1024)
+ image_bytes = bytearray()
+ bytes_downloaded = 0
- # Check actual size after download if Content-Length was not available
- if content_length is None:
- size_mb = len(image_bytes) / (1024 * 1024)
- if size_mb > MAX_IMAGE_URL_DOWNLOAD_SIZE_MB:
+ for chunk in response.iter_bytes(chunk_size=8192):
+ bytes_downloaded += len(chunk)
+ if bytes_downloaded > max_bytes:
+ size_mb = bytes_downloaded / (1024 * 1024)
raise litellm.ImageFetchError(
f"Error: Image size ({size_mb:.2f}MB) exceeds maximum allowed size ({MAX_IMAGE_URL_DOWNLOAD_SIZE_MB}MB). url={url}"
)
+ image_bytes.extend(chunk)
base64_image = base64.b64encode(image_bytes).decode("utf-8")
diff --git a/litellm/litellm_core_utils/redact_messages.py b/litellm/litellm_core_utils/redact_messages.py
index e8c09684323..c268af20e3e 100644
--- a/litellm/litellm_core_utils/redact_messages.py
+++ b/litellm/litellm_core_utils/redact_messages.py
@@ -178,6 +178,11 @@ def perform_redaction(model_call_details: dict, result):
def should_redact_message_logging(model_call_details: dict) -> bool:
"""
Determine if message logging should be redacted.
+
+ Priority order:
+ 1. Dynamic parameter (turn_off_message_logging in request)
+ 2. Headers (litellm-disable-message-redaction / litellm-enable-message-redaction)
+ 3. Global setting (litellm.turn_off_message_logging)
"""
litellm_params = model_call_details.get("litellm_params", {})
@@ -187,36 +192,36 @@ def should_redact_message_logging(model_call_details: dict) -> bool:
# Get headers from the metadata
request_headers = metadata.get("headers", {}) if isinstance(metadata, dict) else {}
- possible_request_headers = [
+ # Check for headers that explicitly control redaction
+ if request_headers and bool(
+ request_headers.get("litellm-disable-message-redaction", False)
+ ):
+ # User explicitly disabled redaction via header
+ return False
+
+ possible_enable_headers = [
"litellm-enable-message-redaction", # old header. maintain backwards compatibility
"x-litellm-enable-message-redaction", # new header
]
is_redaction_enabled_via_header = False
- for header in possible_request_headers:
+ for header in possible_enable_headers:
if bool(request_headers.get(header, False)):
is_redaction_enabled_via_header = True
break
- # check if user opted out of logging message/response to callbacks
- if (
- litellm.turn_off_message_logging is not True
- and is_redaction_enabled_via_header is not True
- and _get_turn_off_message_logging_from_dynamic_params(model_call_details)
- is not True
- ):
- return False
-
- if request_headers and bool(
- request_headers.get("litellm-disable-message-redaction", False)
- ):
- return False
-
- # user has OPTED OUT of message redaction
- if _get_turn_off_message_logging_from_dynamic_params(model_call_details) is False:
- return False
-
- return True
+ # Priority 1: Check dynamic parameter first (if explicitly set)
+ dynamic_turn_off = _get_turn_off_message_logging_from_dynamic_params(model_call_details)
+ if dynamic_turn_off is not None:
+ # Dynamic parameter is explicitly set, use it
+ return dynamic_turn_off
+
+ # Priority 2: Check if header explicitly enables redaction
+ if is_redaction_enabled_via_header:
+ return True
+
+ # Priority 3: Fall back to global setting
+ return litellm.turn_off_message_logging is True
def redact_message_input_output_from_logging(
diff --git a/litellm/litellm_core_utils/streaming_handler.py b/litellm/litellm_core_utils/streaming_handler.py
index 3304759f749..c6f0f67976f 100644
--- a/litellm/litellm_core_utils/streaming_handler.py
+++ b/litellm/litellm_core_utils/streaming_handler.py
@@ -1571,6 +1571,50 @@ class CustomStreamWrapper:
)
return chunk
+ def _add_mcp_list_tools_to_first_chunk(self, chunk: ModelResponseStream) -> ModelResponseStream:
+ """
+ Add mcp_list_tools from _hidden_params to the first chunk's delta.provider_specific_fields.
+
+ This method checks if MCP metadata with mcp_list_tools is stored in _hidden_params
+ and adds it to the first chunk's delta.provider_specific_fields.
+ """
+ try:
+ # Check if MCP metadata should be added to first chunk
+ if not hasattr(self, "_hidden_params") or not self._hidden_params:
+ return chunk
+
+ mcp_metadata = self._hidden_params.get("mcp_metadata")
+ if not mcp_metadata or not isinstance(mcp_metadata, dict):
+ return chunk
+
+ # Only add mcp_list_tools to first chunk (not tool_calls or tool_results)
+ mcp_list_tools = mcp_metadata.get("mcp_list_tools")
+ if not mcp_list_tools:
+ return chunk
+
+ # Add mcp_list_tools to delta.provider_specific_fields
+ if hasattr(chunk, "choices") and chunk.choices:
+ for choice in chunk.choices:
+ if isinstance(choice, StreamingChoices) and hasattr(choice, "delta") and choice.delta:
+ # Get existing provider_specific_fields or create new dict
+ provider_fields = (
+ getattr(choice.delta, "provider_specific_fields", None) or {}
+ )
+
+ # Add only mcp_list_tools to first chunk
+ provider_fields["mcp_list_tools"] = mcp_list_tools
+
+ # Set the provider_specific_fields
+ setattr(choice.delta, "provider_specific_fields", provider_fields)
+
+ except Exception as e:
+ from litellm._logging import verbose_logger
+ verbose_logger.exception(
+ f"Error adding MCP list tools to first chunk: {str(e)}"
+ )
+
+ return chunk
+
def _add_mcp_metadata_to_final_chunk(self, chunk: ModelResponseStream) -> ModelResponseStream:
"""
Add MCP metadata from _hidden_params to the final chunk's delta.provider_specific_fields.
@@ -1727,6 +1771,12 @@ class CustomStreamWrapper:
)
# HANDLE STREAM OPTIONS
self.chunks.append(response)
+
+ # Add mcp_list_tools to first chunk if present
+ if not self.sent_first_chunk:
+ response = self._add_mcp_list_tools_to_first_chunk(response)
+ self.sent_first_chunk = True
+
if hasattr(
response, "usage"
): # remove usage from chunk, only send on final chunk
@@ -1894,6 +1944,11 @@ class CustomStreamWrapper:
input=self.response_uptil_now, model=self.model
)
self.chunks.append(processed_chunk)
+
+ # Add mcp_list_tools to first chunk if present
+ if not self.sent_first_chunk:
+ processed_chunk = self._add_mcp_list_tools_to_first_chunk(processed_chunk)
+ self.sent_first_chunk = True
if hasattr(
processed_chunk, "usage"
): # remove usage from chunk, only send on final chunk
diff --git a/litellm/litellm_core_utils/token_counter.py b/litellm/litellm_core_utils/token_counter.py
index a99bd1cd0f3..6b9e51034c0 100644
--- a/litellm/litellm_core_utils/token_counter.py
+++ b/litellm/litellm_core_utils/token_counter.py
@@ -706,7 +706,7 @@ def _count_content_list(
if isinstance(c, str):
num_tokens += count_function(c)
elif c["type"] == "text":
- num_tokens += count_function(c.get("text", ""))
+ num_tokens += count_function(str(c.get("text", "")))
elif c["type"] == "image_url":
image_url = c.get("image_url")
num_tokens += _count_image_tokens(
@@ -722,7 +722,7 @@ def _count_content_list(
elif c["type"] == "thinking":
# Claude extended thinking content block
# Count the thinking text and skip signature (opaque signature blob)
- thinking_text = c.get("thinking", "")
+ thinking_text = str(c.get("thinking", ""))
if thinking_text:
num_tokens += count_function(thinking_text)
else:
diff --git a/litellm/llms/a2a/__init__.py b/litellm/llms/a2a/__init__.py
new file mode 100644
index 00000000000..043efa5e8bf
--- /dev/null
+++ b/litellm/llms/a2a/__init__.py
@@ -0,0 +1,6 @@
+"""
+A2A (Agent-to-Agent) Protocol Provider for LiteLLM
+"""
+from .chat.transformation import A2AConfig
+
+__all__ = ["A2AConfig"]
diff --git a/litellm/llms/a2a/chat/__init__.py b/litellm/llms/a2a/chat/__init__.py
new file mode 100644
index 00000000000..76bf4dd71d9
--- /dev/null
+++ b/litellm/llms/a2a/chat/__init__.py
@@ -0,0 +1,6 @@
+"""
+A2A Chat Completion Implementation
+"""
+from .transformation import A2AConfig
+
+__all__ = ["A2AConfig"]
diff --git a/litellm/llms/a2a/chat/guardrail_translation/README.md b/litellm/llms/a2a/chat/guardrail_translation/README.md
new file mode 100644
index 00000000000..1e18f5cda3a
--- /dev/null
+++ b/litellm/llms/a2a/chat/guardrail_translation/README.md
@@ -0,0 +1,155 @@
+# A2A Protocol Guardrail Translation Handler
+
+Handler for processing A2A (Agent-to-Agent) Protocol messages with guardrails.
+
+## Overview
+
+This handler processes A2A JSON-RPC 2.0 input/output by:
+1. Extracting text from message parts (`kind: "text"`)
+2. Applying guardrails to text content
+3. Mapping guardrailed text back to original structure
+
+## A2A Protocol Format
+
+### Input Format (JSON-RPC 2.0)
+
+```json
+{
+ "jsonrpc": "2.0",
+ "id": "request-id",
+ "method": "message/send",
+ "params": {
+ "message": {
+ "kind": "message",
+ "messageId": "...",
+ "role": "user",
+ "parts": [
+ {"kind": "text", "text": "Hello, my SSN is 123-45-6789"}
+ ]
+ },
+ "metadata": {
+ "guardrails": ["block-ssn"]
+ }
+ }
+}
+```
+
+### Output Formats
+
+The handler supports multiple A2A response formats:
+
+**Direct message:**
+```json
+{
+ "result": {
+ "kind": "message",
+ "parts": [{"kind": "text", "text": "Response text"}]
+ }
+}
+```
+
+**Nested message:**
+```json
+{
+ "result": {
+ "message": {
+ "parts": [{"kind": "text", "text": "Response text"}]
+ }
+ }
+}
+```
+
+**Task with artifacts:**
+```json
+{
+ "result": {
+ "kind": "task",
+ "artifacts": [
+ {"parts": [{"kind": "text", "text": "Artifact text"}]}
+ ]
+ }
+}
+```
+
+**Task with status message:**
+```json
+{
+ "result": {
+ "kind": "task",
+ "status": {
+ "message": {
+ "parts": [{"kind": "text", "text": "Status message"}]
+ }
+ }
+ }
+}
+```
+
+**Streaming artifact-update:**
+```json
+{
+ "result": {
+ "kind": "artifact-update",
+ "artifact": {
+ "parts": [{"kind": "text", "text": "Streaming text"}]
+ }
+ }
+}
+```
+
+## Usage
+
+The handler is automatically discovered and applied when guardrails are used with A2A endpoints.
+
+### Via LiteLLM Proxy
+
+```bash
+curl -X POST 'http://localhost:4000/a2a/my-agent' \
+-H 'Content-Type: application/json' \
+-H 'Authorization: Bearer your-api-key' \
+-d '{
+ "jsonrpc": "2.0",
+ "id": "1",
+ "method": "message/send",
+ "params": {
+ "message": {
+ "kind": "message",
+ "messageId": "msg-1",
+ "role": "user",
+ "parts": [{"kind": "text", "text": "Hello, my SSN is 123-45-6789"}]
+ },
+ "metadata": {
+ "guardrails": ["block-ssn"]
+ }
+ }
+}'
+```
+
+### Specifying Guardrails
+
+Guardrails can be specified in the A2A request via the `metadata.guardrails` field:
+
+```json
+{
+ "params": {
+ "message": {...},
+ "metadata": {
+ "guardrails": ["block-ssn", "pii-filter"]
+ }
+ }
+}
+```
+
+## Extension
+
+Override these methods to customize behavior:
+
+- `_extract_texts_from_result()`: Custom text extraction from A2A responses
+- `_extract_texts_from_parts()`: Custom text extraction from message parts
+- `_apply_text_to_path()`: Custom application of guardrailed text
+
+## Call Types
+
+This handler is registered for:
+- `CallTypes.send_message`: Synchronous A2A message sending
+- `CallTypes.asend_message`: Asynchronous A2A message sending
diff --git a/litellm/llms/a2a/chat/guardrail_translation/__init__.py b/litellm/llms/a2a/chat/guardrail_translation/__init__.py
new file mode 100644
index 00000000000..13c20677485
--- /dev/null
+++ b/litellm/llms/a2a/chat/guardrail_translation/__init__.py
@@ -0,0 +1,11 @@
+"""A2A Protocol handler for Unified Guardrails."""
+
+from litellm.llms.a2a.chat.guardrail_translation.handler import A2AGuardrailHandler
+from litellm.types.utils import CallTypes
+
+guardrail_translation_mappings = {
+ CallTypes.send_message: A2AGuardrailHandler,
+ CallTypes.asend_message: A2AGuardrailHandler,
+}
+
+__all__ = ["guardrail_translation_mappings"]
diff --git a/litellm/llms/a2a/chat/guardrail_translation/handler.py b/litellm/llms/a2a/chat/guardrail_translation/handler.py
new file mode 100644
index 00000000000..770453f2def
--- /dev/null
+++ b/litellm/llms/a2a/chat/guardrail_translation/handler.py
@@ -0,0 +1,315 @@
+"""
+A2A Protocol Handler for Unified Guardrails
+
+This module provides guardrail translation support for A2A (Agent-to-Agent) Protocol.
+It handles both JSON-RPC 2.0 input requests and output responses, extracting text
+from message parts and applying guardrails.
+
+A2A Protocol Format:
+- Input: JSON-RPC 2.0 with params.message.parts containing text parts
+- Output: JSON-RPC 2.0 with result containing message/artifact parts
+"""
+
+from typing import TYPE_CHECKING, Any, Dict, List, Optional, Tuple, Union
+
+from litellm._logging import verbose_proxy_logger
+from litellm.llms.base_llm.guardrail_translation.base_translation import BaseTranslation
+from litellm.types.utils import GenericGuardrailAPIInputs
+
+if TYPE_CHECKING:
+ from litellm.integrations.custom_guardrail import CustomGuardrail
+ from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj
+ from litellm.proxy._types import UserAPIKeyAuth
+
+
+class A2AGuardrailHandler(BaseTranslation):
+ """
+ Handler for processing A2A Protocol messages with guardrails.
+
+ This class provides methods to:
+ 1. Process input messages (pre-call hook) - extracts text from A2A message parts
+ 2. Process output responses (post-call hook) - extracts text from A2A response parts
+
+ A2A Message Format:
+ - Input: params.message.parts[].text (where kind == "text")
+ - Output: result.message.parts[].text or result.artifacts[].parts[].text
+ """
+
+ async def process_input_messages(
+ self,
+ data: dict,
+ guardrail_to_apply: "CustomGuardrail",
+ litellm_logging_obj: Optional["LiteLLMLoggingObj"] = None,
+ ) -> Any:
+ """
+ Process A2A input messages by applying guardrails to text content.
+
+ Extracts text from A2A message parts and applies guardrails.
+
+ Args:
+ data: The A2A JSON-RPC 2.0 request data
+ guardrail_to_apply: The guardrail instance to apply
+ litellm_logging_obj: Optional logging object
+
+ Returns:
+ Modified data with guardrails applied to text content
+ """
+ # A2A request format: { "params": { "message": { "parts": [...] } } }
+ params = data.get("params", {})
+ message = params.get("message", {})
+ parts = message.get("parts", [])
+
+ if not parts:
+ verbose_proxy_logger.debug("A2A: No parts in message, skipping guardrail")
+ return data
+
+ texts_to_check: List[str] = []
+ text_part_indices: List[int] = [] # Track which parts contain text
+
+ # Step 1: Extract text from all text parts
+ for part_idx, part in enumerate(parts):
+ if part.get("kind") == "text":
+ text = part.get("text", "")
+ if text:
+ texts_to_check.append(text)
+ text_part_indices.append(part_idx)
+
+ # Step 2: Apply guardrail to all texts in batch
+ if texts_to_check:
+ inputs = GenericGuardrailAPIInputs(texts=texts_to_check)
+
+ # Pass the structured A2A message to guardrails
+ inputs["structured_messages"] = [message]
+
+ # Include agent model info if available
+ model = data.get("model")
+ if model:
+ inputs["model"] = model
+
+ guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
+ inputs=inputs,
+ request_data=data,
+ input_type="request",
+ logging_obj=litellm_logging_obj,
+ )
+
+ guardrailed_texts = guardrailed_inputs.get("texts", [])
+
+ # Step 3: Apply guardrailed text back to original parts
+ if guardrailed_texts and len(guardrailed_texts) == len(text_part_indices):
+ for task_idx, part_idx in enumerate(text_part_indices):
+ parts[part_idx]["text"] = guardrailed_texts[task_idx]
+
+ verbose_proxy_logger.debug("A2A: Processed input message: %s", message)
+
+ return data
+
+ async def process_output_response(
+ self,
+ response: Any,
+ guardrail_to_apply: "CustomGuardrail",
+ litellm_logging_obj: Optional["LiteLLMLoggingObj"] = None,
+ user_api_key_dict: Optional["UserAPIKeyAuth"] = None,
+ ) -> Any:
+ """
+ Process A2A output response by applying guardrails to text content.
+
+ Handles multiple A2A response formats:
+ - Direct message: {"result": {"kind": "message", "parts": [...]}}
+ - Nested message: {"result": {"message": {"parts": [...]}}}
+ - Task with artifacts: {"result": {"kind": "task", "artifacts": [{"parts": [...]}]}}
+ - Task with status message: {"result": {"kind": "task", "status": {"message": {"parts": [...]}}}}
+
+ Args:
+ response: A2A JSON-RPC 2.0 response dict or object
+ guardrail_to_apply: The guardrail instance to apply
+ litellm_logging_obj: Optional logging object
+ user_api_key_dict: User API key metadata
+
+ Returns:
+ Modified response with guardrails applied to text content
+ """
+ # Handle both dict and Pydantic model responses
+ if hasattr(response, "model_dump"):
+ response_dict = response.model_dump()
+ is_pydantic = True
+ elif isinstance(response, dict):
+ response_dict = response
+ is_pydantic = False
+ else:
+ verbose_proxy_logger.warning(
+ "A2A: Unknown response type %s, skipping guardrail", type(response)
+ )
+ return response
+
+ result = response_dict.get("result", {})
+ if not result or not isinstance(result, dict):
+ verbose_proxy_logger.debug("A2A: No result in response, skipping guardrail")
+ return response
+
+ # Find all text-containing parts in the response
+ texts_to_check: List[str] = []
+ # Each mapping is (path_to_parts_list, part_index)
+ # path_to_parts_list is a tuple of keys to navigate to the parts list
+ task_mappings: List[Tuple[Tuple[str, ...], int]] = []
+
+ # Extract texts from all possible locations
+ self._extract_texts_from_result(
+ result=result,
+ texts_to_check=texts_to_check,
+ task_mappings=task_mappings,
+ )
+
+ if not texts_to_check:
+ verbose_proxy_logger.debug("A2A: No text content in response")
+ return response
+
+ # Step 2: Apply guardrail to all texts in batch
+ # Create a request_data dict with response info and user API key metadata
+ request_data: dict = {"response": response_dict}
+
+ # Add user API key metadata with prefixed keys
+ user_metadata = self.transform_user_api_key_dict_to_metadata(user_api_key_dict)
+ if user_metadata:
+ request_data["litellm_metadata"] = user_metadata
+
+ inputs = GenericGuardrailAPIInputs(texts=texts_to_check)
+
+ guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
+ inputs=inputs,
+ request_data=request_data,
+ input_type="response",
+ logging_obj=litellm_logging_obj,
+ )
+
+ guardrailed_texts = guardrailed_inputs.get("texts", [])
+
+ # Step 3: Apply guardrailed text back to original response
+ if guardrailed_texts and len(guardrailed_texts) == len(task_mappings):
+ for task_idx, (path, part_idx) in enumerate(task_mappings):
+ self._apply_text_to_path(
+ result=result,
+ path=path,
+ part_idx=part_idx,
+ text=guardrailed_texts[task_idx],
+ )
+
+ verbose_proxy_logger.debug("A2A: Processed output response")
+
+ # Update the original response
+ if is_pydantic:
+ # For Pydantic models, we need to update the underlying dict
+ # and the model will reflect the changes
+ response_dict["result"] = result
+ return response
+ else:
+ response["result"] = result
+ return response
+
+ def _extract_texts_from_result(
+ self,
+ result: Dict[str, Any],
+ texts_to_check: List[str],
+ task_mappings: List[Tuple[Tuple[str, ...], int]],
+ ) -> None:
+ """
+ Extract text from all possible locations in an A2A result.
+
+ Handles multiple response formats:
+ 1. Direct message with parts: {"parts": [...]}
+ 2. Nested message: {"message": {"parts": [...]}}
+ 3. Task with artifacts: {"artifacts": [{"parts": [...]}]}
+ 4. Task with status message: {"status": {"message": {"parts": [...]}}}
+ 5. Streaming artifact-update: {"artifact": {"parts": [...]}}
+ """
+ # Case 1: Direct parts in result (direct message)
+ if "parts" in result:
+ self._extract_texts_from_parts(
+ parts=result["parts"],
+ path=("parts",),
+ texts_to_check=texts_to_check,
+ task_mappings=task_mappings,
+ )
+
+ # Case 2: Nested message
+ message = result.get("message")
+ if message and isinstance(message, dict) and "parts" in message:
+ self._extract_texts_from_parts(
+ parts=message["parts"],
+ path=("message", "parts"),
+ texts_to_check=texts_to_check,
+ task_mappings=task_mappings,
+ )
+
+ # Case 3: Streaming artifact-update (singular artifact)
+ artifact = result.get("artifact")
+ if artifact and isinstance(artifact, dict) and "parts" in artifact:
+ self._extract_texts_from_parts(
+ parts=artifact["parts"],
+ path=("artifact", "parts"),
+ texts_to_check=texts_to_check,
+ task_mappings=task_mappings,
+ )
+
+ # Case 4: Task with status message
+ status = result.get("status", {})
+ if isinstance(status, dict):
+ status_message = status.get("message")
+ if (
+ status_message
+ and isinstance(status_message, dict)
+ and "parts" in status_message
+ ):
+ self._extract_texts_from_parts(
+ parts=status_message["parts"],
+ path=("status", "message", "parts"),
+ texts_to_check=texts_to_check,
+ task_mappings=task_mappings,
+ )
+
+ # Case 5: Task with artifacts (plural, array)
+ artifacts = result.get("artifacts", [])
+ if artifacts and isinstance(artifacts, list):
+ for artifact_idx, art in enumerate(artifacts):
+ if isinstance(art, dict) and "parts" in art:
+ self._extract_texts_from_parts(
+ parts=art["parts"],
+ path=("artifacts", str(artifact_idx), "parts"),
+ texts_to_check=texts_to_check,
+ task_mappings=task_mappings,
+ )
+
+ def _extract_texts_from_parts(
+ self,
+ parts: List[Dict[str, Any]],
+ path: Tuple[str, ...],
+ texts_to_check: List[str],
+ task_mappings: List[Tuple[Tuple[str, ...], int]],
+ ) -> None:
+ """Extract text from message parts."""
+ for part_idx, part in enumerate(parts):
+ if part.get("kind") == "text":
+ text = part.get("text", "")
+ if text:
+ texts_to_check.append(text)
+ task_mappings.append((path, part_idx))
+
+ def _apply_text_to_path(
+ self,
+ result: Dict[Union[str, int], Any],
+ path: Tuple[str, ...],
+ part_idx: int,
+ text: str,
+ ) -> None:
+ """Apply guardrailed text back to the specified path in the result."""
+ # Navigate to the parts list
+ current = result
+ for key in path:
+ if key.isdigit():
+ # Array index
+ current = current[int(key)]
+ else:
+ current = current[key]
+
+ # Update the text in the part
+ current[part_idx]["text"] = text
diff --git a/litellm/llms/a2a/chat/streaming_iterator.py b/litellm/llms/a2a/chat/streaming_iterator.py
new file mode 100644
index 00000000000..4b689414ddd
--- /dev/null
+++ b/litellm/llms/a2a/chat/streaming_iterator.py
@@ -0,0 +1,103 @@
+"""
+A2A Streaming Response Iterator
+"""
+from typing import Optional, Union
+
+from litellm.llms.base_llm.base_model_iterator import BaseModelResponseIterator
+from litellm.types.utils import GenericStreamingChunk, ModelResponseStream
+
+from ..common_utils import extract_text_from_a2a_response
+
+
+class A2AModelResponseIterator(BaseModelResponseIterator):
+ """
+ Iterator for parsing A2A streaming responses.
+
+ Converts A2A JSON-RPC streaming chunks to OpenAI-compatible format.
+ """
+
+ def __init__(
+ self,
+ streaming_response,
+ sync_stream: bool,
+ json_mode: Optional[bool] = False,
+ model: str = "a2a/agent",
+ ):
+ super().__init__(
+ streaming_response=streaming_response,
+ sync_stream=sync_stream,
+ json_mode=json_mode,
+ )
+ self.model = model
+
+ def chunk_parser(self, chunk: dict) -> Union[GenericStreamingChunk, ModelResponseStream]:
+ """
+ Parse A2A streaming chunk to OpenAI format.
+
+ A2A chunk format:
+ {
+ "jsonrpc": "2.0",
+ "id": "request-id",
+ "result": {
+ "message": {
+ "parts": [{"kind": "text", "text": "content"}]
+ }
+ }
+ }
+
+ Or for tasks:
+ {
+ "jsonrpc": "2.0",
+ "result": {
+ "kind": "task",
+ "status": {"state": "running"},
+ "artifacts": [{"parts": [{"kind": "text", "text": "content"}]}]
+ }
+ }
+ """
+ try:
+ # Extract text from A2A response
+ text = extract_text_from_a2a_response(chunk)
+
+ # Determine finish reason
+ finish_reason = self._get_finish_reason(chunk)
+
+ # Return generic streaming chunk
+ return GenericStreamingChunk(
+ text=text,
+ is_finished=bool(finish_reason),
+ finish_reason=finish_reason or "",
+ usage=None,
+ index=0,
+ tool_use=None,
+ )
+ except Exception:
+ # Return empty chunk on parse error
+ return GenericStreamingChunk(
+ text="",
+ is_finished=False,
+ finish_reason="",
+ usage=None,
+ index=0,
+ tool_use=None,
+ )
+
+ def _get_finish_reason(self, chunk: dict) -> Optional[str]:
+ """Extract finish reason from A2A chunk"""
+ result = chunk.get("result", {})
+
+ # Check for task completion
+ if isinstance(result, dict):
+ status = result.get("status", {})
+ if isinstance(status, dict):
+ state = status.get("state")
+ if state == "completed":
+ return "stop"
+ elif state == "failed":
+ return "stop" # Map failed state to 'stop' (valid finish_reason)
+
+ # Check for [DONE] marker
+ if chunk.get("done") is True:
+ return "stop"
+
+ return None
diff --git a/litellm/llms/a2a/chat/transformation.py b/litellm/llms/a2a/chat/transformation.py
new file mode 100644
index 00000000000..163cd5ab22e
--- /dev/null
+++ b/litellm/llms/a2a/chat/transformation.py
@@ -0,0 +1,370 @@
+"""
+A2A Protocol Transformation for LiteLLM
+"""
+import uuid
+from typing import Any, Dict, Iterator, List, Optional, Union
+
+import httpx
+
+from litellm.llms.base_llm.base_model_iterator import BaseModelResponseIterator
+from litellm.llms.base_llm.chat.transformation import BaseConfig, BaseLLMException
+from litellm.types.llms.openai import AllMessageValues
+from litellm.types.utils import Choices, Message, ModelResponse
+
+from ..common_utils import (
+ A2AError,
+ convert_messages_to_prompt,
+ extract_text_from_a2a_response,
+)
+from .streaming_iterator import A2AModelResponseIterator
+
+
+class A2AConfig(BaseConfig):
+ """
+ Configuration for A2A (Agent-to-Agent) Protocol.
+
+ Handles transformation between OpenAI and A2A JSON-RPC 2.0 formats.
+ """
+
+ @staticmethod
+ def resolve_agent_config_from_registry(
+ model: str,
+ api_base: Optional[str],
+ api_key: Optional[str],
+ headers: Optional[Dict[str, Any]],
+ optional_params: Dict[str, Any],
+ ) -> tuple[Optional[str], Optional[str], Optional[Dict[str, Any]]]:
+ """
+ Resolve agent configuration from registry if model format is "a2a/".
+
+ Extracts agent name from model string and looks up configuration in the
+ agent registry (if available in proxy context).
+
+ Args:
+ model: Model string (e.g., "a2a/my-agent")
+ api_base: Explicit api_base (takes precedence over registry)
+ api_key: Explicit api_key (takes precedence over registry)
+ headers: Explicit headers (takes precedence over registry)
+ optional_params: Dict to merge additional litellm_params into
+
+ Returns:
+ Tuple of (api_base, api_key, headers) with registry values filled in
+ """
+ # Extract agent name from model (e.g., "a2a/my-agent" -> "my-agent")
+ agent_name = model.split("/", 1)[1] if "/" in model else None
+
+ # Only lookup if agent name exists and some config is missing
+ if not agent_name or (api_base is not None and api_key is not None and headers is not None):
+ return api_base, api_key, headers
+
+ # Try registry lookup (only available in proxy context)
+ try:
+ from litellm.proxy.agent_endpoints.agent_registry import (
+ global_agent_registry,
+ )
+
+ agent = global_agent_registry.get_agent_by_name(agent_name)
+ if agent:
+ # Get api_base from agent card URL
+ if api_base is None and agent.agent_card_params:
+ api_base = agent.agent_card_params.get("url")
+
+ # Get api_key, headers, and other params from litellm_params
+ if agent.litellm_params:
+ if api_key is None:
+ api_key = agent.litellm_params.get("api_key")
+
+ if headers is None:
+ agent_headers = agent.litellm_params.get("headers")
+ if agent_headers:
+ headers = agent_headers
+
+ # Merge other litellm_params (timeout, max_retries, etc.)
+ for key, value in agent.litellm_params.items():
+ if key not in ["api_key", "api_base", "headers", "model"] and key not in optional_params:
+ optional_params[key] = value
+ except ImportError:
+ pass # Registry not available (not running in proxy context)
+
+ return api_base, api_key, headers
+
+ def get_supported_openai_params(self, model: str) -> List[str]:
+ """Return list of supported OpenAI parameters"""
+ return [
+ "stream",
+ "temperature",
+ "max_tokens",
+ "top_p",
+ ]
+
+ def map_openai_params(
+ self,
+ non_default_params: dict,
+ optional_params: dict,
+ model: str,
+ drop_params: bool,
+ ) -> dict:
+ """
+ Map OpenAI parameters to A2A parameters.
+
+ For A2A protocol, we need to map the stream parameter so
+ transform_request can determine which JSON-RPC method to use.
+ """
+ # Map stream parameter
+ for param, value in non_default_params.items():
+ if param == "stream" and value is True:
+ optional_params["stream"] = value
+
+ return optional_params
+
+ def validate_environment(
+ self,
+ headers: dict,
+ model: str,
+ messages: List[AllMessageValues],
+ optional_params: dict,
+ litellm_params: dict,
+ api_key: Optional[str] = None,
+ api_base: Optional[str] = None,
+ ) -> dict:
+ """
+ Validate environment and set headers for A2A requests.
+
+ Args:
+ headers: Request headers dict
+ model: Model name
+ messages: Messages list
+ optional_params: Optional parameters
+ litellm_params: LiteLLM parameters
+ api_key: API key (optional for A2A)
+ api_base: API base URL
+
+ Returns:
+ Updated headers dict
+ """
+ # Ensure Content-Type is set to application/json for JSON-RPC 2.0
+ if "content-type" not in headers and "Content-Type" not in headers:
+ headers["Content-Type"] = "application/json"
+
+ # Add Authorization header if API key is provided
+ if api_key is not None:
+ headers["Authorization"] = f"Bearer {api_key}"
+
+ return headers
+
+ def get_complete_url(
+ self,
+ api_base: Optional[str],
+ api_key: Optional[str],
+ model: str,
+ optional_params: dict,
+ litellm_params: dict,
+ stream: Optional[bool] = None,
+ ) -> str:
+ """
+ Get the complete A2A agent endpoint URL.
+
+ A2A agents use JSON-RPC 2.0 at the base URL, not specific paths.
+ The method (message/send or message/stream) is specified in the
+ JSON-RPC request body, not in the URL.
+
+ Args:
+ api_base: Base URL of the A2A agent (e.g., "http://0.0.0.0:9999")
+ api_key: API key (not used for URL construction)
+ model: Model name (not used for A2A, agent determined by api_base)
+ optional_params: Optional parameters
+ litellm_params: LiteLLM parameters
+ stream: Whether this is a streaming request (affects JSON-RPC method)
+
+ Returns:
+ Complete URL for the A2A endpoint (base URL)
+ """
+ if api_base is None:
+ raise ValueError("api_base is required for A2A provider")
+
+ # A2A uses JSON-RPC 2.0 at the base URL
+ # Remove trailing slash for consistency
+ return api_base.rstrip("/")
+
+ def transform_request(
+ self,
+ model: str,
+ messages: List[AllMessageValues],
+ optional_params: dict,
+ litellm_params: dict,
+ headers: dict,
+ ) -> dict:
+ """
+ Transform OpenAI request to A2A JSON-RPC 2.0 format.
+
+ Args:
+ model: Model name
+ messages: List of OpenAI messages
+ optional_params: Optional parameters
+ litellm_params: LiteLLM parameters
+ headers: Request headers
+
+ Returns:
+ A2A JSON-RPC 2.0 request dict
+ """
+ # Generate request ID
+ request_id = str(uuid.uuid4())
+
+ if not messages:
+ raise ValueError("At least one message is required for A2A completion")
+
+ # Convert all messages to maintain conversation history
+ # Use helper to format conversation with role prefixes
+ full_context = convert_messages_to_prompt(messages)
+
+ # Create single A2A message with full conversation context
+ a2a_message = {
+ "role": "user",
+ "parts": [{"kind": "text", "text": full_context}],
+ "messageId": str(uuid.uuid4()),
+ }
+
+ # Build JSON-RPC 2.0 request
+ # For A2A protocol, the method is "message/send" for non-streaming
+ # and "message/stream" for streaming
+ stream = optional_params.get("stream", False)
+ method = "message/stream" if stream else "message/send"
+
+ request_data = {
+ "jsonrpc": "2.0",
+ "id": request_id,
+ "method": method,
+ "params": {
+ "message": a2a_message
+ }
+ }
+
+ return request_data
+
+ def transform_response(
+ self,
+ model: str,
+ raw_response: httpx.Response,
+ model_response: ModelResponse,
+ logging_obj: Any,
+ request_data: dict,
+ messages: List[AllMessageValues],
+ optional_params: dict,
+ litellm_params: dict,
+ encoding: Any,
+ api_key: Optional[str] = None,
+ json_mode: Optional[bool] = None,
+ ) -> ModelResponse:
+ """
+ Transform A2A JSON-RPC 2.0 response to OpenAI format.
+
+ Args:
+ model: Model name
+ raw_response: HTTP response from A2A agent
+ model_response: Model response object to populate
+ logging_obj: Logging object
+ request_data: Original request data
+ messages: Original messages
+ optional_params: Optional parameters
+ litellm_params: LiteLLM parameters
+ encoding: Encoding object
+ api_key: API key
+ json_mode: JSON mode flag
+
+ Returns:
+ Populated ModelResponse object
+ """
+ try:
+ response_json = raw_response.json()
+ except Exception as e:
+ raise A2AError(
+ status_code=raw_response.status_code,
+ message=f"Failed to parse A2A response: {str(e)}",
+ headers=dict(raw_response.headers),
+ )
+
+ # Check for JSON-RPC error
+ if "error" in response_json:
+ error = response_json["error"]
+ raise A2AError(
+ status_code=raw_response.status_code,
+ message=f"A2A error: {error.get('message', 'Unknown error')}",
+ headers=dict(raw_response.headers),
+ )
+
+ # Extract text from A2A response
+ text = extract_text_from_a2a_response(response_json)
+
+ # Populate model response
+ model_response.choices = [
+ Choices(
+ finish_reason="stop",
+ index=0,
+ message=Message(
+ content=text,
+ role="assistant",
+ ),
+ )
+ ]
+
+ # Set model
+ model_response.model = model
+
+ # Set ID from response
+ model_response.id = response_json.get("id", str(uuid.uuid4()))
+
+ return model_response
+
+ def get_model_response_iterator(
+ self,
+ streaming_response: Union[Iterator, Any],
+ sync_stream: bool,
+ json_mode: Optional[bool] = False,
+ ) -> BaseModelResponseIterator:
+ """
+ Get streaming iterator for A2A responses.
+
+ Args:
+ streaming_response: Streaming response iterator
+ sync_stream: Whether this is a sync stream
+ json_mode: JSON mode flag
+
+ Returns:
+ A2A streaming iterator
+ """
+ return A2AModelResponseIterator(
+ streaming_response=streaming_response,
+ sync_stream=sync_stream,
+ json_mode=json_mode,
+ )
+
+ def _openai_message_to_a2a_message(self, message: Dict[str, Any]) -> Dict[str, Any]:
+ """
+ Convert OpenAI message to A2A message format.
+
+ Args:
+ message: OpenAI message dict
+
+ Returns:
+ A2A message dict
+ """
+ content = message.get("content", "")
+ role = message.get("role", "user")
+
+ return {
+ "role": role,
+ "parts": [{"kind": "text", "text": str(content)}],
+ "messageId": str(uuid.uuid4()),
+ }
+
+ def get_error_class(
+ self, error_message: str, status_code: int, headers: Union[dict, httpx.Headers]
+ ) -> BaseLLMException:
+ """Return appropriate error class for A2A errors"""
+ # Convert headers to dict if needed
+ headers_dict = dict(headers) if isinstance(headers, httpx.Headers) else headers
+ return A2AError(
+ status_code=status_code,
+ message=error_message,
+ headers=headers_dict,
+ )
diff --git a/litellm/llms/a2a/common_utils.py b/litellm/llms/a2a/common_utils.py
new file mode 100644
index 00000000000..116e1205409
--- /dev/null
+++ b/litellm/llms/a2a/common_utils.py
@@ -0,0 +1,152 @@
+"""
+Common utilities for A2A (Agent-to-Agent) Protocol
+"""
+from typing import Any, Dict, List
+
+from pydantic import BaseModel
+
+from litellm.litellm_core_utils.prompt_templates.common_utils import (
+ convert_content_list_to_str,
+)
+from litellm.llms.base_llm.chat.transformation import BaseLLMException
+from litellm.types.llms.openai import AllMessageValues
+
+
+class A2AError(BaseLLMException):
+ """Base exception for A2A protocol errors"""
+
+ def __init__(
+ self,
+ status_code: int,
+ message: str,
+ headers: Dict[str, Any] = {},
+ ):
+ super().__init__(
+ status_code=status_code,
+ message=message,
+ headers=headers,
+ )
+
+
+def convert_messages_to_prompt(messages: List[AllMessageValues]) -> str:
+ """
+ Convert OpenAI messages to a single prompt string for A2A agent.
+
+ Formats each message as "{role}: {content}" and joins with newlines
+ to preserve conversation history. Handles both string and list content.
+
+ Args:
+ messages: List of OpenAI-format messages
+
+ Returns:
+ Formatted prompt string with full conversation context
+ """
+ conversation_parts = []
+ for msg in messages:
+ # Use LiteLLM's helper to extract text from content (handles both str and list)
+ content_text = convert_content_list_to_str(message=msg)
+
+ # Get role
+ if isinstance(msg, BaseModel):
+ role = msg.model_dump().get("role", "user")
+ elif isinstance(msg, dict):
+ role = msg.get("role", "user")
+ else:
+ role = dict(msg).get("role", "user") # type: ignore
+
+ if content_text:
+ conversation_parts.append(f"{role}: {content_text}")
+
+ return "\n".join(conversation_parts)
+
+
+def extract_text_from_a2a_message(
+ message: Dict[str, Any], depth: int = 0, max_depth: int = 10
+) -> str:
+ """
+ Extract text content from A2A message parts.
+
+ Args:
+ message: A2A message dict with 'parts' containing text parts
+ depth: Current recursion depth (internal use)
+ max_depth: Maximum recursion depth to prevent infinite loops
+
+ Returns:
+ Concatenated text from all text parts
+ """
+ if message is None or depth >= max_depth:
+ return ""
+
+ parts = message.get("parts", [])
+ text_parts: List[str] = []
+
+ for part in parts:
+ if part.get("kind") == "text":
+ text_parts.append(part.get("text", ""))
+ # Handle nested parts if they exist
+ elif "parts" in part:
+ nested_text = extract_text_from_a2a_message(part, depth + 1, max_depth)
+ if nested_text:
+ text_parts.append(nested_text)
+
+ return " ".join(text_parts)
+
+
+def extract_text_from_a2a_response(
+ response_dict: Dict[str, Any], max_depth: int = 10
+) -> str:
+ """
+ Extract text content from A2A response result.
+
+ Args:
+ response_dict: A2A response dict with 'result' containing message
+ max_depth: Maximum recursion depth to prevent infinite loops
+
+ Returns:
+ Text from response message parts
+ """
+ result = response_dict.get("result", {})
+ if not isinstance(result, dict):
+ return ""
+
+ # A2A response can have different formats:
+ # 1. Direct message: {"result": {"kind": "message", "parts": [...]}}
+ # 2. Nested message: {"result": {"message": {"parts": [...]}}}
+ # 3. Task with artifacts: {"result": {"kind": "task", "artifacts": [{"parts": [...]}]}}
+ # 4. Task with status message: {"result": {"kind": "task", "status": {"message": {"parts": [...]}}}}
+ # 5. Streaming artifact-update: {"result": {"kind": "artifact-update", "artifact": {"parts": [...]}}}
+
+ # Check if result itself has parts (direct message)
+ if "parts" in result:
+ return extract_text_from_a2a_message(result, depth=0, max_depth=max_depth)
+
+ # Check for nested message
+ message = result.get("message")
+ if message:
+ return extract_text_from_a2a_message(message, depth=0, max_depth=max_depth)
+
+ # Check for streaming artifact-update (singular artifact)
+ artifact = result.get("artifact")
+ if artifact and isinstance(artifact, dict):
+ return extract_text_from_a2a_message(
+ artifact, depth=0, max_depth=max_depth
+ )
+
+ # Check for task status message (common in Gemini A2A agents)
+ status = result.get("status", {})
+ if isinstance(status, dict):
+ status_message = status.get("message")
+ if status_message:
+ return extract_text_from_a2a_message(
+ status_message, depth=0, max_depth=max_depth
+ )
+
+ # Handle task result with artifacts (plural, array)
+ artifacts = result.get("artifacts", [])
+ if artifacts and len(artifacts) > 0:
+ first_artifact = artifacts[0]
+ return extract_text_from_a2a_message(
+ first_artifact, depth=0, max_depth=max_depth
+ )
+
+ return ""
diff --git a/litellm/llms/anthropic/chat/guardrail_translation/handler.py b/litellm/llms/anthropic/chat/guardrail_translation/handler.py
index 9d50cc4d92d..a14e7d118e8 100644
--- a/litellm/llms/anthropic/chat/guardrail_translation/handler.py
+++ b/litellm/llms/anthropic/chat/guardrail_translation/handler.py
@@ -34,6 +34,7 @@ from litellm.types.llms.openai import (
)
from litellm.types.utils import (
ChatCompletionMessageToolCall,
+ Choices,
GenericGuardrailAPIInputs,
ModelResponse,
)
@@ -74,9 +75,10 @@ class AnthropicMessagesHandler(BaseTranslation):
if messages is None:
return data
- chat_completion_compatible_request = (
+ chat_completion_compatible_request, tool_name_mapping = (
LiteLLMAnthropicMessagesAdapter().translate_anthropic_to_openai(
- anthropic_message_request=cast(AnthropicMessagesRequest, data)
+ # Use a shallow copy to avoid mutating request data (pop on litellm_metadata).
+ anthropic_message_request=cast(AnthropicMessagesRequest, data.copy())
)
)
@@ -84,9 +86,9 @@ class AnthropicMessagesHandler(BaseTranslation):
texts_to_check: List[str] = []
images_to_check: List[str] = []
- tools_to_check: List[ChatCompletionToolParam] = (
- chat_completion_compatible_request.get("tools", [])
- )
+ tools_to_check: List[
+ ChatCompletionToolParam
+ ] = chat_completion_compatible_request.get("tools", [])
task_mappings: List[Tuple[int, Optional[int]]] = []
# Track (message_index, content_index) for each text
# content_index is None for string content, int for list content
@@ -110,6 +112,10 @@ class AnthropicMessagesHandler(BaseTranslation):
inputs["tools"] = tools_to_check
if structured_messages:
inputs["structured_messages"] = structured_messages
+ # Include model information if available
+ model = data.get("model")
+ if model:
+ inputs["model"] = model
guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
inputs=inputs,
request_data=data,
@@ -278,7 +284,10 @@ class AnthropicMessagesHandler(BaseTranslation):
if hasattr(content_block, "model_dump"):
block_dict = content_block.model_dump()
else:
- block_dict = {"type": block_type, "text": getattr(content_block, "text", None)}
+ block_dict = {
+ "type": block_type,
+ "text": getattr(content_block, "text", None),
+ }
else:
continue
@@ -309,6 +318,14 @@ class AnthropicMessagesHandler(BaseTranslation):
inputs["images"] = images_to_check
if tool_calls_to_check:
inputs["tool_calls"] = tool_calls_to_check
+ # Include model information from the response if available
+ response_model = None
+ if isinstance(response, dict):
+ response_model = response.get("model")
+ elif hasattr(response, "model"):
+ response_model = getattr(response, "model", None)
+ if response_model:
+ inputs["model"] = response_model
guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
inputs=inputs,
@@ -346,30 +363,40 @@ class AnthropicMessagesHandler(BaseTranslation):
"""
has_ended = self._check_streaming_has_ended(responses_so_far)
if has_ended:
-
# build the model response from the responses_so_far
- model_response = cast(
- ModelResponse,
- AnthropicPassthroughLoggingHandler._build_complete_streaming_response(
- all_chunks=responses_so_far,
- litellm_logging_obj=cast("LiteLLMLoggingObj", litellm_logging_obj),
- model="",
- ),
+ built_response = AnthropicPassthroughLoggingHandler._build_complete_streaming_response(
+ all_chunks=responses_so_far,
+ litellm_logging_obj=cast("LiteLLMLoggingObj", litellm_logging_obj),
+ model="",
)
- tool_calls_list = cast(Optional[List[ChatCompletionMessageToolCall]], model_response.choices[0].message.tool_calls) # type: ignore
- string_so_far = model_response.choices[0].message.content # type: ignore
- guardrail_inputs = GenericGuardrailAPIInputs()
- if string_so_far:
- guardrail_inputs["texts"] = [string_so_far]
- if tool_calls_list:
- guardrail_inputs["tool_calls"] = tool_calls_list
- _guardrailed_inputs = await guardrail_to_apply.apply_guardrail( # allow rejecting the response, if invalid
- inputs=guardrail_inputs,
- request_data={},
- input_type="response",
- logging_obj=litellm_logging_obj,
- )
+ # Check if model_response is valid and has choices before accessing
+ if (
+ built_response is not None
+ and hasattr(built_response, "choices")
+ and built_response.choices
+ ):
+ model_response = cast(ModelResponse, built_response)
+ first_choice = cast(Choices, model_response.choices[0])
+ tool_calls_list = cast(
+ Optional[List[ChatCompletionMessageToolCall]],
+ first_choice.message.tool_calls,
+ )
+ string_so_far = first_choice.message.content
+ guardrail_inputs = GenericGuardrailAPIInputs()
+ if string_so_far:
+ guardrail_inputs["texts"] = [string_so_far]
+ if tool_calls_list:
+ guardrail_inputs["tool_calls"] = tool_calls_list
+
+ _guardrailed_inputs = await guardrail_to_apply.apply_guardrail( # allow rejecting the response, if invalid
+ inputs=guardrail_inputs,
+ request_data={},
+ input_type="response",
+ logging_obj=litellm_logging_obj,
+ )
+ else:
+ verbose_proxy_logger.debug("Skipping output guardrail - model response has no choices")
return responses_so_far
string_so_far = self.get_streaming_string_so_far(responses_so_far)
@@ -552,7 +579,7 @@ class AnthropicMessagesHandler(BaseTranslation):
response_content = response.get("content", [])
else:
response_content = getattr(response, "content", None) or []
-
+
if not response_content:
return False
for content_block in response_content:
@@ -636,7 +663,10 @@ class AnthropicMessagesHandler(BaseTranslation):
if isinstance(content_block, dict):
if content_block.get("type") == "text":
cast(Dict[str, Any], content_block)["text"] = guardrail_response
- elif hasattr(content_block, "type") and getattr(content_block, "type", None) == "text":
+ elif (
+ hasattr(content_block, "type")
+ and getattr(content_block, "type", None) == "text"
+ ):
# Update Pydantic object's text attribute
if hasattr(content_block, "text"):
content_block.text = guardrail_response
diff --git a/litellm/llms/anthropic/chat/handler.py b/litellm/llms/anthropic/chat/handler.py
index 6a9aafd076b..485e95d6489 100644
--- a/litellm/llms/anthropic/chat/handler.py
+++ b/litellm/llms/anthropic/chat/handler.py
@@ -512,6 +512,9 @@ class ModelResponseIterator:
# Accumulate web_search_tool_result blocks for multi-turn reconstruction
# See: https://github.com/BerriAI/litellm/issues/17737
self.web_search_results: List[Dict[str, Any]] = []
+
+ # Accumulate compaction blocks for multi-turn reconstruction
+ self.compaction_blocks: List[Dict[str, Any]] = []
def check_empty_tool_call_args(self) -> bool:
"""
@@ -592,6 +595,12 @@ class ModelResponseIterator:
)
]
provider_specific_fields["thinking_blocks"] = thinking_blocks
+ elif "content" in content_block["delta"] and content_block["delta"].get("type") == "compaction_delta":
+ # Handle compaction delta
+ provider_specific_fields["compaction_delta"] = {
+ "type": "compaction_delta",
+ "content": content_block["delta"]["content"]
+ }
return text, tool_use, thinking_blocks, provider_specific_fields
@@ -721,6 +730,20 @@ class ModelResponseIterator:
provider_specific_fields=provider_specific_fields,
)
+ elif content_block_start["content_block"]["type"] == "compaction":
+ # Handle compaction blocks
+ # The full content comes in content_block_start
+ self.compaction_blocks.append(
+ content_block_start["content_block"]
+ )
+ provider_specific_fields["compaction_blocks"] = (
+ self.compaction_blocks
+ )
+ provider_specific_fields["compaction_start"] = {
+ "type": "compaction",
+ "content": content_block_start["content_block"].get("content", "")
+ }
+
elif content_block_start["content_block"]["type"].endswith("_tool_result"):
# Handle all tool result types (web_search, bash_code_execution, text_editor, etc.)
content_type = content_block_start["content_block"]["type"]
diff --git a/litellm/llms/anthropic/chat/transformation.py b/litellm/llms/anthropic/chat/transformation.py
index 82eccee596d..02b8d952445 100644
--- a/litellm/llms/anthropic/chat/transformation.py
+++ b/litellm/llms/anthropic/chat/transformation.py
@@ -170,9 +170,10 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
tool_call["caller"] = cast(Dict[str, Any], anthropic_tool_content["caller"]) # type: ignore[typeddict-item]
return tool_call
- def _is_claude_opus_4_5(self, model: str) -> bool:
+ @staticmethod
+ def _is_claude_opus_4_6(model: str) -> bool:
"""Check if the model is Claude Opus 4.5."""
- return "opus-4-5" in model.lower() or "opus_4_5" in model.lower()
+ return "opus-4-6" in model.lower() or "opus_4_6" in model.lower()
def get_supported_openai_params(self, model: str):
params = [
@@ -290,10 +291,19 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
elif tool_choice == "none":
_tool_choice = AnthropicMessagesToolChoice(type="none")
elif isinstance(tool_choice, dict):
- _tool_name = tool_choice.get("function", {}).get("name")
- _tool_choice = AnthropicMessagesToolChoice(type="tool")
- if _tool_name is not None:
- _tool_choice["name"] = _tool_name
+ if "type" in tool_choice and "function" not in tool_choice:
+ tool_type = tool_choice.get("type")
+ if tool_type == "auto":
+ _tool_choice = AnthropicMessagesToolChoice(type="auto")
+ elif tool_type == "required" or tool_type == "any":
+ _tool_choice = AnthropicMessagesToolChoice(type="any")
+ elif tool_type == "none":
+ _tool_choice = AnthropicMessagesToolChoice(type="none")
+ else:
+ _tool_name = tool_choice.get("function", {}).get("name")
+ if _tool_name is not None:
+ _tool_choice = AnthropicMessagesToolChoice(type="tool")
+ _tool_choice["name"] = _tool_name
if parallel_tool_use is not None:
# Anthropic uses 'disable_parallel_tool_use' flag to determine if parallel tool use is allowed
@@ -650,32 +660,38 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
@staticmethod
def _map_reasoning_effort(
- reasoning_effort: Optional[Union[REASONING_EFFORT, str]],
+ reasoning_effort: Optional[Union[REASONING_EFFORT, str]],
+ model: str,
) -> Optional[AnthropicThinkingParam]:
- if reasoning_effort is None:
- return None
- elif reasoning_effort == "low":
+ if AnthropicConfig._is_claude_opus_4_6(model):
return AnthropicThinkingParam(
- type="enabled",
- budget_tokens=DEFAULT_REASONING_EFFORT_LOW_THINKING_BUDGET,
- )
- elif reasoning_effort == "medium":
- return AnthropicThinkingParam(
- type="enabled",
- budget_tokens=DEFAULT_REASONING_EFFORT_MEDIUM_THINKING_BUDGET,
- )
- elif reasoning_effort == "high":
- return AnthropicThinkingParam(
- type="enabled",
- budget_tokens=DEFAULT_REASONING_EFFORT_HIGH_THINKING_BUDGET,
- )
- elif reasoning_effort == "minimal":
- return AnthropicThinkingParam(
- type="enabled",
- budget_tokens=DEFAULT_REASONING_EFFORT_MINIMAL_THINKING_BUDGET,
+ type="adaptive",
)
else:
- raise ValueError(f"Unmapped reasoning effort: {reasoning_effort}")
+ if reasoning_effort is None:
+ return None
+ elif reasoning_effort == "low":
+ return AnthropicThinkingParam(
+ type="enabled",
+ budget_tokens=DEFAULT_REASONING_EFFORT_LOW_THINKING_BUDGET,
+ )
+ elif reasoning_effort == "medium":
+ return AnthropicThinkingParam(
+ type="enabled",
+ budget_tokens=DEFAULT_REASONING_EFFORT_MEDIUM_THINKING_BUDGET,
+ )
+ elif reasoning_effort == "high":
+ return AnthropicThinkingParam(
+ type="enabled",
+ budget_tokens=DEFAULT_REASONING_EFFORT_HIGH_THINKING_BUDGET,
+ )
+ elif reasoning_effort == "minimal":
+ return AnthropicThinkingParam(
+ type="enabled",
+ budget_tokens=DEFAULT_REASONING_EFFORT_MINIMAL_THINKING_BUDGET,
+ )
+ else:
+ raise ValueError(f"Unmapped reasoning effort: {reasoning_effort}")
def _extract_json_schema_from_response_format(
self, value: Optional[dict]
@@ -851,13 +867,8 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
if param == "thinking":
optional_params["thinking"] = value
elif param == "reasoning_effort" and isinstance(value, str):
- # For Claude Opus 4.5, map reasoning_effort to output_config
- if self._is_claude_opus_4_5(model):
- optional_params["output_config"] = {"effort": value}
-
- # For other models, map to thinking parameter
optional_params["thinking"] = AnthropicConfig._map_reasoning_effort(
- value
+ reasoning_effort=value, model=model
)
elif param == "web_search_options" and isinstance(value, dict):
hosted_web_search_tool = self.map_web_search_tool(
@@ -868,6 +879,9 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
)
elif param == "extra_headers":
optional_params["extra_headers"] = value
+ elif param == "context_management" and isinstance(value, dict):
+ # Pass through Anthropic-specific context_management parameter
+ optional_params["context_management"] = value
## handle thinking tokens
self.update_optional_params_with_thinking_tokens(
@@ -1017,9 +1031,37 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
if beta_value not in existing_values:
headers["anthropic-beta"] = f"{existing_beta}, {beta_value}"
- def _ensure_context_management_beta_header(self, headers: dict) -> None:
- beta_value = ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value
- self._ensure_beta_header(headers, beta_value)
+ def _ensure_context_management_beta_header(
+ self, headers: dict, context_management: dict
+ ) -> None:
+ """
+ Add appropriate beta headers based on context_management edits.
+ - If any edit has type "compact_20260112", add compact-2026-01-12 header
+ - For all other edits, add context-management-2025-06-27 header
+ """
+ edits = context_management.get("edits", [])
+
+ has_compact = False
+ has_other = False
+
+ for edit in edits:
+ edit_type = edit.get("type", "")
+ if edit_type == "compact_20260112":
+ has_compact = True
+ else:
+ has_other = True
+
+ # Add compact header if any compact edits exist
+ if has_compact:
+ self._ensure_beta_header(
+ headers, ANTHROPIC_BETA_HEADER_VALUES.COMPACT_2026_01_12.value
+ )
+
+ # Add context management header if any other edits exist
+ if has_other:
+ self._ensure_beta_header(
+ headers, ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value
+ )
def update_headers_with_optional_anthropic_beta(
self, headers: dict, optional_params: dict
@@ -1047,7 +1089,9 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
headers, ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value
)
if optional_params.get("context_management") is not None:
- self._ensure_context_management_beta_header(headers)
+ self._ensure_context_management_beta_header(
+ headers, optional_params["context_management"]
+ )
if optional_params.get("output_format") is not None:
self._ensure_beta_header(
headers, ANTHROPIC_BETA_HEADER_VALUES.STRUCTURED_OUTPUT_2025_09_25.value
@@ -1216,6 +1260,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
List[ChatCompletionToolCallChunk],
Optional[List[Any]],
Optional[List[Any]],
+ Optional[List[Any]],
]:
text_content = ""
citations: Optional[List[Any]] = None
@@ -1228,6 +1273,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
tool_calls: List[ChatCompletionToolCallChunk] = []
web_search_results: Optional[List[Any]] = None
tool_results: Optional[List[Any]] = None
+ compaction_blocks: Optional[List[Any]] = None
for idx, content in enumerate(completion_response["content"]):
if content["type"] == "text":
text_content += content["text"]
@@ -1269,6 +1315,12 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
thinking_blocks.append(
cast(ChatCompletionRedactedThinkingBlock, content)
)
+
+ ## COMPACTION
+ elif content["type"] == "compaction":
+ if compaction_blocks is None:
+ compaction_blocks = []
+ compaction_blocks.append(content)
## CITATIONS
if content.get("citations") is not None:
@@ -1290,7 +1342,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
if thinking_content is not None:
reasoning_content += thinking_content
- return text_content, citations, thinking_blocks, reasoning_content, tool_calls, web_search_results, tool_results
+ return text_content, citations, thinking_blocks, reasoning_content, tool_calls, web_search_results, tool_results, compaction_blocks
def calculate_usage(
self,
@@ -1307,6 +1359,10 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
cache_creation_token_details: Optional[CacheCreationTokenDetails] = None
web_search_requests: Optional[int] = None
tool_search_requests: Optional[int] = None
+ inference_geo: Optional[str] = None
+ if "inference_geo" in _usage and _usage["inference_geo"] is not None:
+ inference_geo = _usage["inference_geo"]
+
if (
"cache_creation_input_tokens" in _usage
and _usage["cache_creation_input_tokens"] is not None
@@ -1369,7 +1425,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
else 0
)
completion_token_details = CompletionTokensDetailsWrapper(
- reasoning_tokens=reasoning_tokens if reasoning_tokens > 0 else None,
+ reasoning_tokens=reasoning_tokens if reasoning_tokens > 0 else 0,
text_tokens=completion_tokens - reasoning_tokens if reasoning_tokens > 0 else completion_tokens,
)
total_tokens = prompt_tokens + completion_tokens
@@ -1390,6 +1446,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
if (web_search_requests is not None or tool_search_requests is not None)
else None
),
+ inference_geo=inference_geo,
)
return usage
@@ -1433,6 +1490,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
tool_calls,
web_search_results,
tool_results,
+ compaction_blocks,
) = self.extract_response_content(completion_response=completion_response)
if (
@@ -1460,6 +1518,8 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
provider_specific_fields["tool_results"] = tool_results
if container is not None:
provider_specific_fields["container"] = container
+ if compaction_blocks is not None:
+ provider_specific_fields["compaction_blocks"] = compaction_blocks
_message = litellm.Message(
tool_calls=tool_calls,
@@ -1468,6 +1528,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
thinking_blocks=thinking_blocks,
reasoning_content=reasoning_content,
)
+ _message.provider_specific_fields = provider_specific_fields
## HANDLE JSON MODE - anthropic returns single function call
json_mode_message = self._transform_response_for_json_mode(
@@ -1498,18 +1559,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
model_response.created = int(time.time())
model_response.model = completion_response["model"]
- context_management_response = completion_response.get("context_management")
- if context_management_response is not None:
- _hidden_params["context_management"] = context_management_response
- try:
- model_response.__dict__["context_management"] = (
- context_management_response
- )
- except Exception:
- pass
-
model_response._hidden_params = _hidden_params
-
return model_response
def get_prefix_prompt(self, messages: List[AllMessageValues]) -> Optional[str]:
diff --git a/litellm/llms/anthropic/cost_calculation.py b/litellm/llms/anthropic/cost_calculation.py
index 8f34eb00ce5..11b61cc92f0 100644
--- a/litellm/llms/anthropic/cost_calculation.py
+++ b/litellm/llms/anthropic/cost_calculation.py
@@ -22,10 +22,17 @@ def cost_per_token(model: str, usage: "Usage") -> Tuple[float, float]:
Returns:
Tuple[float, float] - prompt_cost_in_usd, completion_cost_in_usd
"""
- return generic_cost_per_token(
- model=model, usage=usage, custom_llm_provider="anthropic"
+ # If usage has inference_geo, prepend it as prefix to model name
+ if hasattr(usage, "inference_geo") and usage.inference_geo and usage.inference_geo.lower() not in ["global", "not_available"]:
+ model_with_geo_prefix = f"{usage.inference_geo}/{model}"
+ else:
+ model_with_geo_prefix = model
+ prompt_cost, completion_cost = generic_cost_per_token(
+ model=model_with_geo_prefix, usage=usage, custom_llm_provider="anthropic"
)
+ return prompt_cost, completion_cost
+
def get_cost_for_anthropic_web_search(
model_info: Optional["ModelInfo"] = None,
diff --git a/litellm/llms/anthropic/experimental_pass_through/adapters/handler.py b/litellm/llms/anthropic/experimental_pass_through/adapters/handler.py
index 8fa7bb7e65e..a17eba75b3b 100644
--- a/litellm/llms/anthropic/experimental_pass_through/adapters/handler.py
+++ b/litellm/llms/anthropic/experimental_pass_through/adapters/handler.py
@@ -6,6 +6,7 @@ from typing import (
Dict,
List,
Optional,
+ Tuple,
Union,
cast,
)
@@ -47,8 +48,14 @@ class LiteLLMMessagesToCompletionTransformationHandler:
top_p: Optional[float] = None,
output_format: Optional[Dict] = None,
extra_kwargs: Optional[Dict[str, Any]] = None,
- ) -> Dict[str, Any]:
- """Prepare kwargs for litellm.completion/acompletion"""
+ ) -> Tuple[Dict[str, Any], Dict[str, str]]:
+ """Prepare kwargs for litellm.completion/acompletion.
+
+ Returns:
+ Tuple of (completion_kwargs, tool_name_mapping)
+ - tool_name_mapping maps truncated tool names back to original names
+ for tools that exceeded OpenAI's 64-char limit
+ """
from litellm.litellm_core_utils.litellm_logging import (
Logging as LiteLLMLoggingObject,
)
@@ -80,7 +87,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
if output_format:
request_data["output_format"] = output_format
- openai_request = ANTHROPIC_ADAPTER.translate_completion_input_params(
+ openai_request, tool_name_mapping = ANTHROPIC_ADAPTER.translate_completion_input_params_with_tool_mapping(
request_data
)
@@ -116,7 +123,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
):
completion_kwargs[key] = value
- return completion_kwargs
+ return completion_kwargs, tool_name_mapping
@staticmethod
async def async_anthropic_messages_handler(
@@ -137,7 +144,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
**kwargs,
) -> Union[AnthropicMessagesResponse, AsyncIterator]:
"""Handle non-Anthropic models asynchronously using the adapter"""
- completion_kwargs = (
+ completion_kwargs, tool_name_mapping = (
LiteLLMMessagesToCompletionTransformationHandler._prepare_completion_kwargs(
max_tokens=max_tokens,
messages=messages,
@@ -164,6 +171,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
ANTHROPIC_ADAPTER.translate_completion_output_params_streaming(
completion_response,
model=model,
+ tool_name_mapping=tool_name_mapping,
)
)
if transformed_stream is not None:
@@ -172,7 +180,8 @@ class LiteLLMMessagesToCompletionTransformationHandler:
else:
anthropic_response = (
ANTHROPIC_ADAPTER.translate_completion_output_params(
- cast(ModelResponse, completion_response)
+ cast(ModelResponse, completion_response),
+ tool_name_mapping=tool_name_mapping,
)
)
if anthropic_response is not None:
@@ -222,7 +231,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
**kwargs,
)
- completion_kwargs = (
+ completion_kwargs, tool_name_mapping = (
LiteLLMMessagesToCompletionTransformationHandler._prepare_completion_kwargs(
max_tokens=max_tokens,
messages=messages,
@@ -249,6 +258,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
ANTHROPIC_ADAPTER.translate_completion_output_params_streaming(
completion_response,
model=model,
+ tool_name_mapping=tool_name_mapping,
)
)
if transformed_stream is not None:
@@ -257,7 +267,8 @@ class LiteLLMMessagesToCompletionTransformationHandler:
else:
anthropic_response = (
ANTHROPIC_ADAPTER.translate_completion_output_params(
- cast(ModelResponse, completion_response)
+ cast(ModelResponse, completion_response),
+ tool_name_mapping=tool_name_mapping,
)
)
if anthropic_response is not None:
diff --git a/litellm/llms/anthropic/experimental_pass_through/adapters/streaming_iterator.py b/litellm/llms/anthropic/experimental_pass_through/adapters/streaming_iterator.py
index 24524233ddf..a86820f82e8 100644
--- a/litellm/llms/anthropic/experimental_pass_through/adapters/streaming_iterator.py
+++ b/litellm/llms/anthropic/experimental_pass_through/adapters/streaming_iterator.py
@@ -3,7 +3,7 @@
import json
import traceback
from collections import deque
-from typing import TYPE_CHECKING, Any, AsyncIterator, Iterator, Literal, Optional
+from typing import TYPE_CHECKING, Any, AsyncIterator, Dict, Iterator, Literal, Optional
from litellm import verbose_logger
from litellm._uuid import uuid
@@ -44,9 +44,16 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
pending_new_content_block: bool = False
chunk_queue: deque = deque() # Queue for buffering multiple chunks
- def __init__(self, completion_stream: Any, model: str):
+ def __init__(
+ self,
+ completion_stream: Any,
+ model: str,
+ tool_name_mapping: Optional[Dict[str, str]] = None,
+ ):
super().__init__(completion_stream)
self.model = model
+ # Mapping of truncated tool names to original names (for OpenAI's 64-char limit)
+ self.tool_name_mapping = tool_name_mapping or {}
def _create_initial_usage_delta(self) -> UsageDelta:
"""
@@ -401,6 +408,19 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
choices=chunk.choices # type: ignore
)
+ # Restore original tool name if it was truncated for OpenAI's 64-char limit
+ if block_type == "tool_use":
+ # Type narrowing: content_block_start is ToolUseBlock when block_type is "tool_use"
+ from typing import cast
+ from litellm.types.llms.anthropic import ToolUseBlock
+
+ tool_block = cast(ToolUseBlock, content_block_start)
+
+ if tool_block.get("name"):
+ truncated_name = tool_block["name"]
+ original_name = self.tool_name_mapping.get(truncated_name, truncated_name)
+ tool_block["name"] = original_name
+
if block_type != self.current_content_block_type:
self.current_content_block_type = block_type
self.current_content_block_start = content_block_start
@@ -408,9 +428,14 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
# For parallel tool calls, we'll necessarily have a new content block
# if we get a function name since it signals a new tool call
- if block_type == "tool_use" and content_block_start.get("name"):
- self.current_content_block_type = block_type
- self.current_content_block_start = content_block_start
- return True
+ if block_type == "tool_use":
+ from typing import cast
+ from litellm.types.llms.anthropic import ToolUseBlock
+
+ tool_block = cast(ToolUseBlock, content_block_start)
+ if tool_block.get("name"):
+ self.current_content_block_type = block_type
+ self.current_content_block_start = content_block_start
+ return True
return False
diff --git a/litellm/llms/anthropic/experimental_pass_through/adapters/transformation.py b/litellm/llms/anthropic/experimental_pass_through/adapters/transformation.py
index 1706f045f14..169b138a5f7 100644
--- a/litellm/llms/anthropic/experimental_pass_through/adapters/transformation.py
+++ b/litellm/llms/anthropic/experimental_pass_through/adapters/transformation.py
@@ -1,3 +1,4 @@
+import hashlib
import json
from typing import (
TYPE_CHECKING,
@@ -12,6 +13,54 @@ from typing import (
cast,
)
+# OpenAI has a 64-character limit for function/tool names
+# Anthropic does not have this limit, so we need to truncate long names
+OPENAI_MAX_TOOL_NAME_LENGTH = 64
+TOOL_NAME_HASH_LENGTH = 8
+TOOL_NAME_PREFIX_LENGTH = OPENAI_MAX_TOOL_NAME_LENGTH - TOOL_NAME_HASH_LENGTH - 1 # 55
+
+
+def truncate_tool_name(name: str) -> str:
+ """
+ Truncate tool names that exceed OpenAI's 64-character limit.
+
+ Uses format: {55-char-prefix}_{8-char-hash} to avoid collisions
+ when multiple tools have similar long names.
+
+ Args:
+ name: The original tool name
+
+ Returns:
+ The original name if <= 64 chars, otherwise truncated with hash
+ """
+ if len(name) <= OPENAI_MAX_TOOL_NAME_LENGTH:
+ return name
+
+ # Create deterministic hash from full name to avoid collisions
+ name_hash = hashlib.sha256(name.encode()).hexdigest()[:TOOL_NAME_HASH_LENGTH]
+ return f"{name[:TOOL_NAME_PREFIX_LENGTH]}_{name_hash}"
+
+
+def create_tool_name_mapping(
+ tools: List[Dict[str, Any]],
+) -> Dict[str, str]:
+ """
+ Create a mapping of truncated tool names to original names.
+
+ Args:
+ tools: List of tool definitions with 'name' field
+
+ Returns:
+ Dict mapping truncated names to original names (only for truncated tools)
+ """
+ mapping: Dict[str, str] = {}
+ for tool in tools:
+ original_name = tool.get("name", "")
+ truncated_name = truncate_tool_name(original_name)
+ if truncated_name != original_name:
+ mapping[truncated_name] = original_name
+ return mapping
+
from openai.types.chat.chat_completion_chunk import Choice as OpenAIStreamingChoice
from litellm.litellm_core_utils.prompt_templates.common_utils import (
@@ -77,8 +126,29 @@ class AnthropicAdapter:
self, kwargs
) -> Optional[ChatCompletionRequest]:
"""
+ Translate Anthropic request params to OpenAI format.
+
- translate params, where needed
- pass rest, as is
+
+ Note: Use translate_completion_input_params_with_tool_mapping() if you need
+ the tool name mapping for restoring original names in responses.
+ """
+ result, _ = self.translate_completion_input_params_with_tool_mapping(kwargs)
+ return result
+
+ def translate_completion_input_params_with_tool_mapping(
+ self, kwargs
+ ) -> Tuple[Optional[ChatCompletionRequest], Dict[str, str]]:
+ """
+ Translate Anthropic request params to OpenAI format, returning tool name mapping.
+
+ This method handles truncation of tool names that exceed OpenAI's 64-character
+ limit. The mapping allows restoring original names when translating responses.
+
+ Returns:
+ Tuple of (openai_request, tool_name_mapping)
+ - tool_name_mapping maps truncated tool names back to original names
"""
#########################################################
@@ -102,26 +172,51 @@ class AnthropicAdapter:
model=model, messages=messages, **kwargs
)
- translated_body = (
+ translated_body, tool_name_mapping = (
LiteLLMAnthropicMessagesAdapter().translate_anthropic_to_openai(
anthropic_message_request=request_body
)
)
- return translated_body
+ return translated_body, tool_name_mapping
def translate_completion_output_params(
- self, response: ModelResponse
+ self,
+ response: ModelResponse,
+ tool_name_mapping: Optional[Dict[str, str]] = None,
) -> Optional[AnthropicMessagesResponse]:
+ """
+ Translate OpenAI response to Anthropic format.
+
+ Args:
+ response: The OpenAI ModelResponse
+ tool_name_mapping: Optional mapping of truncated tool names to original names.
+ Used to restore original names for tools that exceeded
+ OpenAI's 64-char limit.
+ """
return LiteLLMAnthropicMessagesAdapter().translate_openai_response_to_anthropic(
- response=response
+ response=response,
+ tool_name_mapping=tool_name_mapping,
)
def translate_completion_output_params_streaming(
- self, completion_stream: Any, model: str
+ self,
+ completion_stream: Any,
+ model: str,
+ tool_name_mapping: Optional[Dict[str, str]] = None,
) -> Union[AsyncIterator[bytes], None]:
+ """
+ Translate OpenAI streaming response to Anthropic format.
+
+ Args:
+ completion_stream: The OpenAI streaming response
+ model: The model name
+ tool_name_mapping: Optional mapping of truncated tool names to original names.
+ """
anthropic_wrapper = AnthropicStreamWrapper(
- completion_stream=completion_stream, model=model
+ completion_stream=completion_stream,
+ model=model,
+ tool_name_mapping=tool_name_mapping,
)
# Return the SSE-wrapped version for proper event formatting
return anthropic_wrapper.async_anthropic_sse_wrapper()
@@ -168,6 +263,36 @@ class LiteLLMAnthropicMessagesAdapter:
return provider_specific_fields.get("signature")
return None
+ def _add_cache_control_if_applicable(
+ self,
+ source: Any,
+ target: Any,
+ model: Optional[str],
+ ) -> None:
+ """
+ Extract cache_control from source and add to target if it should be preserved.
+
+ This method accepts Any type to support both regular dicts and TypedDict objects.
+ TypedDict objects (like ChatCompletionTextObject, ChatCompletionImageObject, etc.)
+ are dicts at runtime but have specific types at type-check time. Using Any allows
+ this method to work with both while maintaining runtime correctness.
+
+ Args:
+ source: Dict or TypedDict containing potential cache_control field
+ target: Dict or TypedDict to add cache_control to
+ model: Model name to check if cache_control should be preserved
+ """
+ # TypedDict objects are dicts at runtime, so .get() works
+ cache_control = source.get("cache_control") if isinstance(source, dict) else getattr(source, "cache_control", None)
+ if cache_control and model and self.is_anthropic_claude_model(model):
+ # TypedDict objects support dict operations at runtime
+ # Use type ignore consistent with codebase pattern (see anthropic/chat/transformation.py:432)
+ if isinstance(target, dict):
+ target["cache_control"] = cache_control # type: ignore[typeddict-item]
+ else:
+ # Fallback for non-dict objects (shouldn't happen in practice)
+ cast(Dict[str, Any], target)["cache_control"] = cache_control
+
def translatable_anthropic_params(self) -> List:
"""
Which anthropic params, we need to translate to the openai format.
@@ -205,12 +330,8 @@ class LiteLLMAnthropicMessagesAdapter:
text_obj = ChatCompletionTextObject(
type="text", text=content.get("text", "")
)
- # Preserve cache_control if present (for prompt caching)
- # Only for Anthropic models that support prompt caching
- cache_control = content.get("cache_control")
- if cache_control and model and self.is_anthropic_claude_model(model):
- text_obj["cache_control"] = cache_control # type: ignore
- new_user_content_list.append(text_obj)
+ self._add_cache_control_if_applicable(content, text_obj, model)
+ new_user_content_list.append(text_obj) # type: ignore
elif content.get("type") == "image":
# Convert Anthropic image format to OpenAI format
source = content.get("source", {})
@@ -225,7 +346,24 @@ class LiteLLMAnthropicMessagesAdapter:
image_obj = ChatCompletionImageObject(
type="image_url", image_url=image_url_obj
)
- new_user_content_list.append(image_obj)
+ self._add_cache_control_if_applicable(content, image_obj, model)
+ new_user_content_list.append(image_obj) # type: ignore
+ elif content.get("type") == "document":
+ # Convert Anthropic document format (PDF, etc.) to OpenAI format
+ source = content.get("source", {})
+ openai_image_url = (
+ self._translate_anthropic_image_to_openai(cast(dict, source))
+ )
+
+ if openai_image_url:
+ image_url_obj = ChatCompletionImageUrlObject(
+ url=openai_image_url
+ )
+ doc_obj = ChatCompletionImageObject(
+ type="image_url", image_url=image_url_obj
+ )
+ self._add_cache_control_if_applicable(content, doc_obj, model)
+ new_user_content_list.append(doc_obj) # type: ignore
elif content.get("type") == "tool_result":
if "content" not in content:
tool_result = ChatCompletionToolMessage(
@@ -233,14 +371,16 @@ class LiteLLMAnthropicMessagesAdapter:
tool_call_id=content.get("tool_use_id", ""),
content="",
)
- tool_message_list.append(tool_result)
+ self._add_cache_control_if_applicable(content, tool_result, model)
+ tool_message_list.append(tool_result) # type: ignore[arg-type]
elif isinstance(content.get("content"), str):
tool_result = ChatCompletionToolMessage(
role="tool",
tool_call_id=content.get("tool_use_id", ""),
content=str(content.get("content", "")),
)
- tool_message_list.append(tool_result)
+ self._add_cache_control_if_applicable(content, tool_result, model)
+ tool_message_list.append(tool_result) # type: ignore[arg-type]
elif isinstance(content.get("content"), list):
# Combine all content items into a single tool message
# to avoid creating multiple tool_result blocks with the same ID
@@ -256,7 +396,8 @@ class LiteLLMAnthropicMessagesAdapter:
tool_call_id=content.get("tool_use_id", ""),
content=c,
)
- tool_message_list.append(tool_result)
+ self._add_cache_control_if_applicable(content, tool_result, model)
+ tool_message_list.append(tool_result) # type: ignore[arg-type]
elif isinstance(c, dict):
if c.get("type") == "text":
tool_result = ChatCompletionToolMessage(
@@ -266,7 +407,8 @@ class LiteLLMAnthropicMessagesAdapter:
),
content=c.get("text", ""),
)
- tool_message_list.append(tool_result)
+ self._add_cache_control_if_applicable(content, tool_result, model)
+ tool_message_list.append(tool_result) # type: ignore[arg-type]
elif c.get("type") == "image":
source = c.get("source", {})
openai_image_url = (
@@ -282,7 +424,8 @@ class LiteLLMAnthropicMessagesAdapter:
),
content=openai_image_url,
)
- tool_message_list.append(tool_result)
+ self._add_cache_control_if_applicable(content, tool_result, model)
+ tool_message_list.append(tool_result) # type: ignore[arg-type]
else:
# For multiple content items, combine into a single tool message
# with list content to preserve all items while having one tool_use_id
@@ -331,7 +474,8 @@ class LiteLLMAnthropicMessagesAdapter:
tool_call_id=content.get("tool_use_id", ""),
content=combined_content_parts, # type: ignore
)
- tool_message_list.append(tool_result)
+ self._add_cache_control_if_applicable(content, tool_result, model)
+ tool_message_list.append(tool_result) # type: ignore[arg-type]
if len(tool_message_list) > 0:
new_messages.extend(tool_message_list)
@@ -344,6 +488,8 @@ class LiteLLMAnthropicMessagesAdapter:
## ASSISTANT MESSAGE ##
assistant_message_str: Optional[str] = None
+ assistant_content_list: List[Dict[str, Any]] = [] # For content blocks with cache_control
+ has_cache_control_in_text = False
tool_calls: List[ChatCompletionAssistantToolCall] = []
thinking_blocks: List[
Union[ChatCompletionThinkingBlock, ChatCompletionRedactedThinkingBlock]
@@ -357,13 +503,19 @@ class LiteLLMAnthropicMessagesAdapter:
assistant_message_str = str(content)
elif isinstance(content, dict):
if content.get("type") == "text":
- if assistant_message_str is None:
- assistant_message_str = content.get("text", "")
- else:
- assistant_message_str += content.get("text", "")
+ text_block: Dict[str, Any] = {
+ "type": "text",
+ "text": content.get("text", ""),
+ }
+ self._add_cache_control_if_applicable(content, text_block, model)
+ if "cache_control" in text_block:
+ has_cache_control_in_text = True
+ assistant_content_list.append(text_block)
elif content.get("type") == "tool_use":
+ # Truncate tool name for OpenAI's 64-char limit
+ tool_name = truncate_tool_name(content.get("name", ""))
function_chunk: ChatCompletionToolCallFunctionChunk = {
- "name": content.get("name", ""),
+ "name": tool_name,
"arguments": json.dumps(content.get("input", {})),
}
signature = (
@@ -384,13 +536,13 @@ class LiteLLMAnthropicMessagesAdapter:
provider_specific_fields
)
- tool_calls.append(
- ChatCompletionAssistantToolCall(
- id=content.get("id", ""),
- type="function",
- function=function_chunk,
- )
+ tool_call = ChatCompletionAssistantToolCall(
+ id=content.get("id", ""),
+ type="function",
+ function=function_chunk,
)
+ self._add_cache_control_if_applicable(content, tool_call, model)
+ tool_calls.append(tool_call)
elif content.get("type") == "thinking":
thinking_block = ChatCompletionThinkingBlock(
type="thinking",
@@ -411,18 +563,30 @@ class LiteLLMAnthropicMessagesAdapter:
if (
assistant_message_str is not None
+ or len(assistant_content_list) > 0
or len(tool_calls) > 0
or len(thinking_blocks) > 0
):
+ # Use list format if any text block has cache_control, otherwise use string
+ if has_cache_control_in_text and len(assistant_content_list) > 0:
+ assistant_content: Any = assistant_content_list
+ elif len(assistant_content_list) > 0 and not has_cache_control_in_text:
+ # Concatenate text blocks into string when no cache_control
+ assistant_content = "".join(
+ block.get("text", "") for block in assistant_content_list
+ )
+ else:
+ assistant_content = assistant_message_str
+
assistant_message = ChatCompletionAssistantMessage(
role="assistant",
- content=assistant_message_str,
+ content=assistant_content,
thinking_blocks=(
thinking_blocks if len(thinking_blocks) > 0 else None
),
)
if len(tool_calls) > 0:
- assistant_message["tool_calls"] = tool_calls
+ assistant_message["tool_calls"] = tool_calls # type: ignore
if len(thinking_blocks) > 0:
assistant_message["thinking_blocks"] = thinking_blocks # type: ignore
new_messages.append(assistant_message)
@@ -520,8 +684,11 @@ class LiteLLMAnthropicMessagesAdapter:
elif tool_choice["type"] == "auto":
return "auto"
elif tool_choice["type"] == "tool":
+ # Truncate tool name if it exceeds OpenAI's 64-char limit
+ original_name = tool_choice.get("name", "")
+ truncated_name = truncate_tool_name(original_name)
tc_function_param = ChatCompletionToolChoiceFunctionParam(
- name=tool_choice.get("name", "")
+ name=truncated_name
)
return ChatCompletionToolChoiceObjectParam(
type="function", function=tc_function_param
@@ -532,13 +699,29 @@ class LiteLLMAnthropicMessagesAdapter:
)
def translate_anthropic_tools_to_openai(
- self, tools: List[AllAnthropicToolsValues]
- ) -> List[ChatCompletionToolParam]:
+ self, tools: List[AllAnthropicToolsValues], model: Optional[str] = None
+ ) -> Tuple[List[ChatCompletionToolParam], Dict[str, str]]:
+ """
+ Translate Anthropic tools to OpenAI format.
+
+ Returns:
+ Tuple of (translated_tools, tool_name_mapping)
+ - tool_name_mapping maps truncated names back to original names
+ for tools that exceeded OpenAI's 64-char limit
+ """
new_tools: List[ChatCompletionToolParam] = []
- mapped_tool_params = ["name", "input_schema", "description"]
+ tool_name_mapping: Dict[str, str] = {}
+ mapped_tool_params = ["name", "input_schema", "description", "cache_control"]
for tool in tools:
+ original_name = tool["name"]
+ truncated_name = truncate_tool_name(original_name)
+
+ # Store mapping if name was truncated
+ if truncated_name != original_name:
+ tool_name_mapping[truncated_name] = original_name
+
function_chunk = ChatCompletionToolParamFunctionChunk(
- name=tool["name"],
+ name=truncated_name,
)
if "input_schema" in tool:
function_chunk["parameters"] = tool["input_schema"] # type: ignore
@@ -548,11 +731,11 @@ class LiteLLMAnthropicMessagesAdapter:
for k, v in tool.items():
if k not in mapped_tool_params: # pass additional computer kwargs
function_chunk.setdefault("parameters", {}).update({k: v})
- new_tools.append(
- ChatCompletionToolParam(type="function", function=function_chunk)
- )
+ tool_param = ChatCompletionToolParam(type="function", function=function_chunk)
+ self._add_cache_control_if_applicable(tool, tool_param, model)
+ new_tools.append(tool_param) # type: ignore[arg-type]
- return new_tools
+ return new_tools, tool_name_mapping # type: ignore[return-value]
def translate_anthropic_output_format_to_openai(
self, output_format: Any
@@ -590,14 +773,55 @@ class LiteLLMAnthropicMessagesAdapter:
},
}
+ def _add_system_message_to_messages(
+ self,
+ new_messages: List[AllMessageValues],
+ anthropic_message_request: AnthropicMessagesRequest,
+ ) -> None:
+ """Add system message to messages list if present in request."""
+ if "system" not in anthropic_message_request:
+ return
+ system_content = anthropic_message_request["system"]
+ if not system_content:
+ return
+ # Handle system as string or array of content blocks
+ if isinstance(system_content, str):
+ new_messages.insert(
+ 0,
+ ChatCompletionSystemMessage(role="system", content=system_content),
+ )
+ elif isinstance(system_content, list):
+ # Convert Anthropic system content blocks to OpenAI format
+ openai_system_content: List[Dict[str, Any]] = []
+ model_name = anthropic_message_request.get("model", "")
+ for block in system_content:
+ if isinstance(block, dict) and block.get("type") == "text":
+ text_block: Dict[str, Any] = {
+ "type": "text",
+ "text": block.get("text", ""),
+ }
+ self._add_cache_control_if_applicable(block, text_block, model_name)
+ openai_system_content.append(text_block)
+ if openai_system_content:
+ new_messages.insert(
+ 0,
+ ChatCompletionSystemMessage(role="system", content=openai_system_content), # type: ignore
+ )
+
def translate_anthropic_to_openai(
self, anthropic_message_request: AnthropicMessagesRequest
- ) -> ChatCompletionRequest:
+ ) -> Tuple[ChatCompletionRequest, Dict[str, str]]:
"""
This is used by the beta Anthropic Adapter, for translating anthropic `/v1/messages` requests to the openai format.
+
+ Returns:
+ Tuple of (openai_request, tool_name_mapping)
+ - tool_name_mapping maps truncated tool names back to original names
+ for tools that exceeded OpenAI's 64-char limit
"""
# Debug: Processing Anthropic message request
new_messages: List[AllMessageValues] = []
+ tool_name_mapping: Dict[str, str] = {}
## CONVERT ANTHROPIC MESSAGES TO OPENAI
messages_list: List[
@@ -618,13 +842,7 @@ class LiteLLMAnthropicMessagesAdapter:
model=anthropic_message_request.get("model"),
)
## ADD SYSTEM MESSAGE TO MESSAGES
- if "system" in anthropic_message_request:
- system_content = anthropic_message_request["system"]
- if system_content:
- new_messages.insert(
- 0,
- ChatCompletionSystemMessage(role="system", content=system_content),
- )
+ self._add_system_message_to_messages(new_messages, anthropic_message_request)
new_kwargs: ChatCompletionRequest = {
"model": anthropic_message_request["model"],
@@ -654,8 +872,9 @@ class LiteLLMAnthropicMessagesAdapter:
if "tools" in anthropic_message_request:
tools = anthropic_message_request["tools"]
if tools:
- new_kwargs["tools"] = self.translate_anthropic_tools_to_openai(
- tools=cast(List[AllAnthropicToolsValues], tools)
+ new_kwargs["tools"], tool_name_mapping = self.translate_anthropic_tools_to_openai(
+ tools=cast(List[AllAnthropicToolsValues], tools),
+ model=new_kwargs.get("model"),
)
## CONVERT THINKING
@@ -687,7 +906,7 @@ class LiteLLMAnthropicMessagesAdapter:
if k not in translatable_params: # pass remaining params as is
new_kwargs[k] = v # type: ignore
- return new_kwargs
+ return new_kwargs, tool_name_mapping
def _translate_anthropic_image_to_openai(self, image_source: dict) -> Optional[str]:
"""
@@ -716,22 +935,12 @@ class LiteLLMAnthropicMessagesAdapter:
return None
- def _translate_openai_content_to_anthropic(self, choices: List[Choices]) -> List[
- Union[
- AnthropicResponseContentBlockText,
- AnthropicResponseContentBlockToolUse,
- AnthropicResponseContentBlockThinking,
- AnthropicResponseContentBlockRedactedThinking,
- ]
- ]:
- new_content: List[
- Union[
- AnthropicResponseContentBlockText,
- AnthropicResponseContentBlockToolUse,
- AnthropicResponseContentBlockThinking,
- AnthropicResponseContentBlockRedactedThinking,
- ]
- ] = []
+ def _translate_openai_content_to_anthropic(
+ self,
+ choices: List[Choices],
+ tool_name_mapping: Optional[Dict[str, str]] = None,
+ ) -> List[Dict[str, Any]]:
+ new_content: List[Dict[str, Any]] = []
for choice in choices:
# Handle thinking blocks first
if (
@@ -755,7 +964,7 @@ class LiteLLMAnthropicMessagesAdapter:
if signature_value is not None
else None
),
- )
+ ).model_dump()
)
elif thinking_block.get("type") == "redacted_thinking":
data_value = thinking_block.get("data", "")
@@ -763,15 +972,27 @@ class LiteLLMAnthropicMessagesAdapter:
AnthropicResponseContentBlockRedactedThinking(
type="redacted_thinking",
data=str(data_value) if data_value is not None else "",
- )
+ ).model_dump()
)
+ # Handle reasoning_content when thinking_blocks is not present
+ elif (
+ hasattr(choice.message, "reasoning_content")
+ and choice.message.reasoning_content
+ ):
+ new_content.append(
+ AnthropicResponseContentBlockThinking(
+ type="thinking",
+ thinking=str(choice.message.reasoning_content),
+ signature=None,
+ ).model_dump()
+ )
# Handle text content
if choice.message.content is not None:
new_content.append(
AnthropicResponseContentBlockText(
type="text", text=choice.message.content
- )
+ ).model_dump()
)
# Handle tool calls (in parallel to text content)
if (
@@ -786,13 +1007,21 @@ class LiteLLMAnthropicMessagesAdapter:
if signature:
provider_specific_fields["signature"] = signature
+ # Restore original tool name if it was truncated
+ truncated_name = tool_call.function.name or ""
+ original_name = (
+ tool_name_mapping.get(truncated_name, truncated_name)
+ if tool_name_mapping
+ else truncated_name
+ )
+
tool_use_block = AnthropicResponseContentBlockToolUse(
type="tool_use",
id=tool_call.id,
- name=tool_call.function.name or "",
+ name=original_name,
input=parse_tool_call_arguments(
tool_call.function.arguments,
- tool_name=tool_call.function.name,
+ tool_name=original_name,
context="Anthropic pass-through adapter",
),
)
@@ -801,7 +1030,7 @@ class LiteLLMAnthropicMessagesAdapter:
tool_use_block.provider_specific_fields = (
provider_specific_fields
)
- new_content.append(tool_use_block)
+ new_content.append(tool_use_block.model_dump())
return new_content
@@ -817,10 +1046,24 @@ class LiteLLMAnthropicMessagesAdapter:
return "end_turn"
def translate_openai_response_to_anthropic(
- self, response: ModelResponse
+ self,
+ response: ModelResponse,
+ tool_name_mapping: Optional[Dict[str, str]] = None,
) -> AnthropicMessagesResponse:
+ """
+ Translate OpenAI response to Anthropic format.
+
+ Args:
+ response: The OpenAI ModelResponse
+ tool_name_mapping: Optional mapping of truncated tool names to original names.
+ Used to restore original names for tools that exceeded
+ OpenAI's 64-char limit.
+ """
## translate content block
- anthropic_content = self._translate_openai_content_to_anthropic(choices=response.choices) # type: ignore
+ anthropic_content = self._translate_openai_content_to_anthropic(
+ choices=response.choices, # type: ignore
+ tool_name_mapping=tool_name_mapping,
+ )
## extract finish reason
anthropic_finish_reason = self._translate_openai_finish_reason_to_anthropic(
openai_finish_reason=response.choices[0].finish_reason # type: ignore
@@ -843,7 +1086,7 @@ class LiteLLMAnthropicMessagesAdapter:
role="assistant",
model=response.model or "unknown-model",
stop_sequence=None,
- usage=anthropic_usage,
+ usage=anthropic_usage, # type: ignore
content=anthropic_content, # type: ignore
stop_reason=anthropic_finish_reason,
)
@@ -939,6 +1182,13 @@ class LiteLLMAnthropicMessagesAdapter:
reasoning_content += thinking
reasoning_signature += signature
+ # Handle reasoning_content when thinking_blocks is not present
+ # This handles providers like OpenRouter that return reasoning_content
+ elif isinstance(choice, StreamingChoices) and hasattr(
+ choice.delta, "reasoning_content"
+ ):
+ if choice.delta.reasoning_content is not None:
+ reasoning_content += choice.delta.reasoning_content
if reasoning_content and reasoning_signature:
raise ValueError(
@@ -992,7 +1242,7 @@ class LiteLLMAnthropicMessagesAdapter:
else:
usage_delta = UsageDelta(input_tokens=0, output_tokens=0)
return MessageBlockDelta(
- type="message_delta", delta=delta, usage=usage_delta
+ type="message_delta", delta=delta, usage=usage_delta # type: ignore
)
(
type_of_content,
diff --git a/litellm/llms/anthropic/experimental_pass_through/messages/transformation.py b/litellm/llms/anthropic/experimental_pass_through/messages/transformation.py
index 308bf367d06..bb40f9df266 100644
--- a/litellm/llms/anthropic/experimental_pass_through/messages/transformation.py
+++ b/litellm/llms/anthropic/experimental_pass_through/messages/transformation.py
@@ -2,6 +2,9 @@ from typing import Any, AsyncIterator, Dict, List, Optional, Tuple
import httpx
+from litellm.anthropic_beta_headers_manager import (
+ update_headers_with_filtered_beta,
+)
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj
from litellm.litellm_core_utils.litellm_logging import verbose_logger
from litellm.llms.base_llm.anthropic_messages.transformation import (
@@ -90,6 +93,11 @@ class AnthropicMessagesConfig(BaseAnthropicMessagesConfig):
optional_params=optional_params,
)
+ headers = update_headers_with_filtered_beta(
+ headers=headers,
+ provider="anthropic",
+ )
+
return headers, api_base
def transform_anthropic_messages_request(
@@ -189,8 +197,27 @@ class AnthropicMessagesConfig(BaseAnthropicMessagesConfig):
beta_values.update(b.strip() for b in existing_beta.split(","))
# Check for context management
- if optional_params.get("context_management") is not None:
- beta_values.add(ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value)
+ context_management_param = optional_params.get("context_management")
+ if context_management_param is not None:
+ # Check edits array for compact_20260112 type
+ edits = context_management_param.get("edits", [])
+ has_compact = False
+ has_other = False
+
+ for edit in edits:
+ edit_type = edit.get("type", "")
+ if edit_type == "compact_20260112":
+ has_compact = True
+ else:
+ has_other = True
+
+ # Add compact header if any compact edits exist
+ if has_compact:
+ beta_values.add(ANTHROPIC_BETA_HEADER_VALUES.COMPACT_2026_01_12.value)
+
+ # Add context management header if any other edits exist
+ if has_other:
+ beta_values.add(ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value)
# Check for structured outputs
if optional_params.get("output_format") is not None:
diff --git a/litellm/llms/azure/batches/handler.py b/litellm/llms/azure/batches/handler.py
index 3996cb808e4..aaefe801687 100644
--- a/litellm/llms/azure/batches/handler.py
+++ b/litellm/llms/azure/batches/handler.py
@@ -5,12 +5,10 @@ Azure Batches API Handler
from typing import Any, Coroutine, Optional, Union, cast
import httpx
-
from openai import AsyncOpenAI, OpenAI
from litellm.llms.azure.azure import AsyncAzureOpenAI, AzureOpenAI
from litellm.types.llms.openai import (
- Batch,
CancelBatchRequest,
CreateBatchRequest,
RetrieveBatchRequest,
@@ -130,9 +128,9 @@ class AzureBatchesAPI(BaseAzureLLM):
self,
cancel_batch_data: CancelBatchRequest,
client: Union[AsyncAzureOpenAI, AsyncOpenAI],
- ) -> Batch:
+ ) -> LiteLLMBatch:
response = await client.batches.cancel(**cancel_batch_data)
- return response
+ return LiteLLMBatch(**response.model_dump())
def cancel_batch(
self,
@@ -160,8 +158,23 @@ class AzureBatchesAPI(BaseAzureLLM):
raise ValueError(
"OpenAI client is not initialized. Make sure api_key is passed or OPENAI_API_KEY is set in the environment."
)
+
+ if _is_async is True:
+ if not isinstance(azure_client, (AsyncAzureOpenAI, AsyncOpenAI)):
+ raise ValueError(
+ "Azure client is not an instance of AsyncAzureOpenAI or AsyncOpenAI. Make sure you passed an async client."
+ )
+ return self.acancel_batch( # type: ignore
+ cancel_batch_data=cancel_batch_data, client=azure_client
+ )
+
+ # At this point, azure_client is guaranteed to be a sync client
+ if not isinstance(azure_client, (AzureOpenAI, OpenAI)):
+ raise ValueError(
+ "Azure client is not an instance of AzureOpenAI or OpenAI. Make sure you passed a sync client."
+ )
response = azure_client.batches.cancel(**cancel_batch_data)
- return response
+ return LiteLLMBatch(**response.model_dump())
async def alist_batches(
self,
diff --git a/litellm/llms/azure/chat/gpt_5_transformation.py b/litellm/llms/azure/chat/gpt_5_transformation.py
index 506b7fdfe5e..eeb55911ecf 100644
--- a/litellm/llms/azure/chat/gpt_5_transformation.py
+++ b/litellm/llms/azure/chat/gpt_5_transformation.py
@@ -22,7 +22,8 @@ class AzureOpenAIGPT5Config(AzureOpenAIConfig, OpenAIGPT5Config):
Accepts both explicit gpt-5 model names and the ``gpt5_series/`` prefix
used for manual routing.
"""
- return "gpt-5" in model or "gpt5_series" in model
+ # gpt-5-chat* is a chat model and shouldn't go through GPT-5 reasoning restrictions.
+ return ("gpt-5" in model and "gpt-5-chat" not in model) or "gpt5_series" in model
def get_supported_openai_params(self, model: str) -> List[str]:
"""Get supported parameters for Azure OpenAI GPT-5 models.
@@ -37,6 +38,11 @@ class AzureOpenAIGPT5Config(AzureOpenAIConfig, OpenAIGPT5Config):
"""
params = OpenAIGPT5Config.get_supported_openai_params(self, model=model)
+ # Azure supports tool_choice for GPT-5 deployments, but the base GPT-5 config
+ # can drop it when the deployment name isn't in the OpenAI model registry.
+ if "tool_choice" not in params:
+ params.append("tool_choice")
+
# Only gpt-5.2 has been verified to support logprobs on Azure
if self.is_model_gpt_5_2_model(model):
azure_supported_params = ["logprobs", "top_logprobs"]
diff --git a/litellm/llms/azure/cost_calculation.py b/litellm/llms/azure/cost_calculation.py
index 96c58d95ff2..5b411095ea1 100644
--- a/litellm/llms/azure/cost_calculation.py
+++ b/litellm/llms/azure/cost_calculation.py
@@ -1,11 +1,12 @@
"""
Helper util for handling azure openai-specific cost calculation
-- e.g.: prompt caching
+- e.g.: prompt caching, audio tokens
"""
from typing import Optional, Tuple
from litellm._logging import verbose_logger
+from litellm.litellm_core_utils.llm_cost_calc.utils import generic_cost_per_token
from litellm.types.utils import Usage
from litellm.utils import get_model_info
@@ -18,34 +19,15 @@ def cost_per_token(
Input:
- model: str, the model name without provider prefix
- - usage: LiteLLM Usage block, containing anthropic caching information
+ - usage: LiteLLM Usage block, containing caching and audio token information
Returns:
Tuple[float, float] - prompt_cost_in_usd, completion_cost_in_usd
"""
## GET MODEL INFO
model_info = get_model_info(model=model, custom_llm_provider="azure")
- cached_tokens: Optional[int] = None
- ## CALCULATE INPUT COST
- non_cached_text_tokens = usage.prompt_tokens
- if usage.prompt_tokens_details and usage.prompt_tokens_details.cached_tokens:
- cached_tokens = usage.prompt_tokens_details.cached_tokens
- non_cached_text_tokens = non_cached_text_tokens - cached_tokens
- prompt_cost: float = non_cached_text_tokens * model_info["input_cost_per_token"]
- ## CALCULATE OUTPUT COST
- completion_cost: float = (
- usage["completion_tokens"] * model_info["output_cost_per_token"]
- )
-
- ## Prompt Caching cost calculation
- if model_info.get("cache_read_input_token_cost") is not None and cached_tokens:
- # Note: We read ._cache_read_input_tokens from the Usage - since cost_calculator.py standardizes the cache read tokens on usage._cache_read_input_tokens
- prompt_cost += cached_tokens * (
- model_info.get("cache_read_input_token_cost", 0) or 0
- )
-
- ## Speech / Audio cost calculation
+ ## Speech / Audio cost calculation (cost per second for TTS models)
if (
"output_cost_per_second" in model_info
and model_info["output_cost_per_second"] is not None
@@ -55,7 +37,14 @@ def cost_per_token(
f"For model={model} - output_cost_per_second: {model_info.get('output_cost_per_second')}; response time: {response_time_ms}"
)
## COST PER SECOND ##
- prompt_cost = 0
+ prompt_cost = 0.0
completion_cost = model_info["output_cost_per_second"] * response_time_ms / 1000
+ return prompt_cost, completion_cost
- return prompt_cost, completion_cost
+ ## Use generic cost calculator for all other cases
+ ## This properly handles: text tokens, audio tokens, cached tokens, reasoning tokens, etc.
+ return generic_cost_per_token(
+ model=model,
+ usage=usage,
+ custom_llm_provider="azure",
+ )
diff --git a/litellm/llms/azure/responses/transformation.py b/litellm/llms/azure/responses/transformation.py
index d621cb209d7..44ce368fd49 100644
--- a/litellm/llms/azure/responses/transformation.py
+++ b/litellm/llms/azure/responses/transformation.py
@@ -1,4 +1,5 @@
from typing import TYPE_CHECKING, Any, Dict, List, Literal, Optional, Tuple, Union
+from copy import deepcopy
import httpx
from openai.types.responses import ResponseReasoningItem
@@ -43,7 +44,7 @@ class AzureOpenAIResponsesAPIConfig(OpenAIResponsesAPIConfig):
"""
Handle reasoning items to filter out the status field.
Issue: https://github.com/BerriAI/litellm/issues/13484
-
+
Azure OpenAI API does not accept 'status' field in reasoning input items.
"""
if item.get("type") == "reasoning":
@@ -78,7 +79,7 @@ class AzureOpenAIResponsesAPIConfig(OpenAIResponsesAPIConfig):
}
return filtered_item
return item
-
+
def _validate_input_param(
self, input: Union[str, ResponseInputParam]
) -> Union[str, ResponseInputParam]:
@@ -90,7 +91,7 @@ class AzureOpenAIResponsesAPIConfig(OpenAIResponsesAPIConfig):
# First call parent's validation
validated_input = super()._validate_input_param(input)
-
+
# Then filter out status from message items
if isinstance(validated_input, list):
filtered_input: List[Any] = []
@@ -102,7 +103,7 @@ class AzureOpenAIResponsesAPIConfig(OpenAIResponsesAPIConfig):
else:
filtered_input.append(item)
return cast(ResponseInputParam, filtered_input)
-
+
return validated_input
def transform_responses_api_request(
@@ -116,6 +117,21 @@ class AzureOpenAIResponsesAPIConfig(OpenAIResponsesAPIConfig):
"""No transform applied since inputs are in OpenAI spec already"""
stripped_model_name = self.get_stripped_model_name(model)
+ # Azure Responses API requires flattened tools (params at top level, not nested in 'function')
+ if "tools" in response_api_optional_request_params and isinstance(
+ response_api_optional_request_params["tools"], list
+ ):
+ new_tools: List[Dict[str, Any]] = []
+ for tool in response_api_optional_request_params["tools"]:
+ if isinstance(tool, dict) and "function" in tool:
+ new_tool: Dict[str, Any] = deepcopy(tool)
+ function_data = new_tool.pop("function")
+ new_tool.update(function_data)
+ new_tools.append(new_tool)
+ else:
+ new_tools.append(tool)
+ response_api_optional_request_params["tools"] = new_tools
+
return super().transform_responses_api_request(
model=stripped_model_name,
input=input,
diff --git a/litellm/llms/azure_ai/anthropic/count_tokens/transformation.py b/litellm/llms/azure_ai/anthropic/count_tokens/transformation.py
index e284595cc8a..09b83b7c971 100644
--- a/litellm/llms/azure_ai/anthropic/count_tokens/transformation.py
+++ b/litellm/llms/azure_ai/anthropic/count_tokens/transformation.py
@@ -30,30 +30,32 @@ class AzureAIAnthropicCountTokensConfig(AnthropicCountTokensConfig):
"""
Get the required headers for the Azure AI Anthropic CountTokens API.
- Uses Azure authentication (api-key header) instead of Anthropic's x-api-key.
+ Azure AI Anthropic uses Anthropic's native API format, which requires the
+ x-api-key header for authentication (in addition to Azure's api-key header).
Args:
api_key: The Azure AI API key
litellm_params: Optional LiteLLM parameters for additional auth config
Returns:
- Dictionary of required headers with Azure authentication
+ Dictionary of required headers with both x-api-key and Azure authentication
"""
- # Start with base headers
+ # Start with base headers including x-api-key for Anthropic API compatibility
headers = {
"Content-Type": "application/json",
"anthropic-version": "2023-06-01",
"anthropic-beta": ANTHROPIC_TOKEN_COUNTING_BETA_VERSION,
+ "x-api-key": api_key, # Azure AI Anthropic requires this header
}
- # Use Azure authentication
+ # Also set up Azure auth headers for flexibility
litellm_params = litellm_params or {}
if "api_key" not in litellm_params:
litellm_params["api_key"] = api_key
litellm_params_obj = GenericLiteLLMParams(**litellm_params)
- # Get Azure auth headers
+ # Get Azure auth headers (api-key or Authorization)
azure_headers = BaseAzureLLM._base_validate_azure_environment(
headers={}, litellm_params=litellm_params_obj
)
@@ -68,7 +70,7 @@ class AzureAIAnthropicCountTokensConfig(AnthropicCountTokensConfig):
Get the Azure AI Anthropic CountTokens API endpoint.
Args:
- api_base: The Azure AI API base URL
+ api_base: The Azure AI API base URL
(e.g., https://my-resource.services.ai.azure.com or
https://my-resource.services.ai.azure.com/anthropic)
diff --git a/litellm/llms/azure_ai/anthropic/transformation.py b/litellm/llms/azure_ai/anthropic/transformation.py
index 2d8d3b987c7..753bc9c08eb 100644
--- a/litellm/llms/azure_ai/anthropic/transformation.py
+++ b/litellm/llms/azure_ai/anthropic/transformation.py
@@ -3,6 +3,9 @@ Azure Anthropic transformation config - extends AnthropicConfig with Azure authe
"""
from typing import TYPE_CHECKING, Dict, List, Optional, Union
+from litellm.anthropic_beta_headers_manager import (
+ update_headers_with_filtered_beta,
+)
from litellm.llms.anthropic.chat.transformation import AnthropicConfig
from litellm.llms.azure.common_utils import BaseAzureLLM
from litellm.types.llms.openai import AllMessageValues
@@ -87,6 +90,12 @@ class AzureAnthropicConfig(AnthropicConfig):
if "anthropic-version" not in headers:
headers["anthropic-version"] = "2023-06-01"
+ # Filter out unsupported beta headers for Azure AI
+ headers = update_headers_with_filtered_beta(
+ headers=headers,
+ provider="azure_ai",
+ )
+
return headers
def transform_request(
diff --git a/litellm/llms/azure_ai/azure_model_router/__init__.py b/litellm/llms/azure_ai/azure_model_router/__init__.py
new file mode 100644
index 00000000000..0165d60b643
--- /dev/null
+++ b/litellm/llms/azure_ai/azure_model_router/__init__.py
@@ -0,0 +1,4 @@
+"""Azure AI Foundry Model Router support."""
+from .transformation import AzureModelRouterConfig
+
+__all__ = ["AzureModelRouterConfig"]
diff --git a/litellm/llms/azure_ai/azure_model_router/transformation.py b/litellm/llms/azure_ai/azure_model_router/transformation.py
new file mode 100644
index 00000000000..3d6dc53c515
--- /dev/null
+++ b/litellm/llms/azure_ai/azure_model_router/transformation.py
@@ -0,0 +1,125 @@
+"""
+Transformation for Azure AI Foundry Model Router.
+
+The Model Router is a special Azure AI deployment that automatically routes requests
+to the best available model. It has specific cost tracking requirements.
+"""
+from typing import Any, List, Optional
+
+from httpx import Response
+
+from litellm.llms.azure_ai.chat.transformation import AzureAIStudioConfig
+from litellm.llms.base_llm.chat.transformation import LiteLLMLoggingObj
+from litellm.types.llms.openai import AllMessageValues
+from litellm.types.utils import ModelResponse
+
+
+class AzureModelRouterConfig(AzureAIStudioConfig):
+ """
+ Configuration for Azure AI Foundry Model Router.
+
+ Handles:
+ - Stripping model_router prefix before sending to Azure API
+ - Preserving full model path in responses for cost tracking
+ - Calculating flat infrastructure costs for Model Router
+ """
+
+ def transform_request(
+ self,
+ model: str,
+ messages: List[AllMessageValues],
+ optional_params: dict,
+ litellm_params: dict,
+ headers: dict,
+ ) -> dict:
+ """
+ Transform request for Model Router.
+
+ Strips the model_router/ prefix so only the deployment name is sent to Azure.
+ Example: model_router/azure-model-router -> azure-model-router
+ """
+ from litellm.llms.azure_ai.common_utils import AzureFoundryModelInfo
+
+ # Get base model name (strips routing prefixes like model_router/)
+ base_model: str = AzureFoundryModelInfo.get_base_model(model)
+
+ return super().transform_request(
+ base_model, messages, optional_params, litellm_params, headers
+ )
+
+ def transform_response(
+ self,
+ model: str,
+ raw_response: Response,
+ model_response: ModelResponse,
+ logging_obj: LiteLLMLoggingObj,
+ request_data: dict,
+ messages: List[AllMessageValues],
+ optional_params: dict,
+ litellm_params: dict,
+ encoding: Any,
+ api_key: Optional[str] = None,
+ json_mode: Optional[bool] = None,
+ ) -> ModelResponse:
+ """
+ Transform response for Model Router.
+
+ Preserves the original model path (including model_router/ prefix) in the response
+ for proper cost tracking and logging.
+ """
+ from litellm.llms.azure_ai.common_utils import AzureFoundryModelInfo
+
+ # Preserve the original model from litellm_params (includes routing prefixes like model_router/)
+ # This ensures cost tracking and logging use the full model path
+ original_model: str = litellm_params.get("model") or model
+ if not original_model.startswith("azure_ai/"):
+ # Add provider prefix if not already present
+ model_response.model = f"azure_ai/{original_model}"
+ else:
+ model_response.model = original_model
+
+ # Get base model for the parent call (strips routing prefixes for API compatibility)
+ base_model: str = AzureFoundryModelInfo.get_base_model(model)
+
+ return super().transform_response(
+ model=base_model,
+ raw_response=raw_response,
+ model_response=model_response,
+ logging_obj=logging_obj,
+ request_data=request_data,
+ messages=messages,
+ optional_params=optional_params,
+ litellm_params=litellm_params,
+ encoding=encoding,
+ api_key=api_key,
+ json_mode=json_mode,
+ )
+
+ def calculate_additional_costs(
+ self, model: str, prompt_tokens: int, completion_tokens: int
+ ) -> Optional[dict]:
+ """
+ Calculate additional costs for Azure Model Router.
+
+ Adds a flat infrastructure cost of $0.14 per M input tokens for using the Model Router.
+
+ Args:
+ model: The model name (should be a model router model)
+ prompt_tokens: Number of prompt tokens
+ completion_tokens: Number of completion tokens
+
+ Returns:
+ Dictionary with additional costs, or None if not applicable.
+ """
+ from litellm.llms.azure_ai.cost_calculator import (
+ calculate_azure_model_router_flat_cost,
+ )
+
+ flat_cost = calculate_azure_model_router_flat_cost(
+ model=model, prompt_tokens=prompt_tokens
+ )
+
+ if flat_cost > 0:
+ return {"Azure Model Router Flat Cost": flat_cost}
+
+ return None
diff --git a/litellm/llms/azure_ai/common_utils.py b/litellm/llms/azure_ai/common_utils.py
index 01a3f5766c6..47d397d6e98 100644
--- a/litellm/llms/azure_ai/common_utils.py
+++ b/litellm/llms/azure_ai/common_utils.py
@@ -13,14 +13,28 @@ class AzureFoundryModelInfo(BaseLLMModelInfo):
self._model = model
@staticmethod
- def get_azure_ai_route(model: str) -> Literal["agents", "default"]:
+ def get_azure_ai_route(model: str) -> Literal["agents", "model_router", "default"]:
"""
Get the Azure AI route for the given model.
Similar to BedrockModelInfo.get_bedrock_route().
+
+ Supported routes:
+ - agents: azure_ai/agents/
+ - model_router: azure_ai/model_router/ or models with "model-router"/"model_router" in name
+ - default: standard models
"""
if "agents/" in model:
return "agents"
+ # Detect model router by prefix (model_router/) or by name containing "model-router"/"model_router"
+ model_lower = model.lower()
+ if (
+ "model_router/" in model_lower
+ or "model-router/" in model_lower
+ or "model-router" in model_lower
+ or "model_router" in model_lower
+ ):
+ return "model_router"
return "default"
@staticmethod
@@ -75,8 +89,73 @@ class AzureFoundryModelInfo(BaseLLMModelInfo):
#########################################################
@staticmethod
- def get_base_model(model: str) -> Optional[str]:
- raise NotImplementedError("Azure Foundry does not support base model")
+ def strip_model_router_prefix(model: str) -> str:
+ """
+ Strip the model_router prefix from model name.
+
+ Examples:
+ - "model_router/gpt-4o" -> "gpt-4o"
+ - "model-router/gpt-4o" -> "gpt-4o"
+ - "gpt-4o" -> "gpt-4o"
+
+ Args:
+ model: Model name potentially with model_router prefix
+
+ Returns:
+ Model name without the prefix
+ """
+ if "model_router/" in model:
+ return model.split("model_router/", 1)[1]
+ if "model-router/" in model:
+ return model.split("model-router/", 1)[1]
+ return model
+
+ @staticmethod
+ def get_base_model(model: str) -> str:
+ """
+ Get the base model name, stripping any Azure AI routing prefixes.
+
+ Args:
+ model: Model name potentially with routing prefixes
+
+ Returns:
+ Base model name
+ """
+ # Strip model_router prefix if present
+ model = AzureFoundryModelInfo.strip_model_router_prefix(model)
+ return model
+
+ @staticmethod
+ def get_azure_ai_config_for_model(model: str):
+ """
+ Get the appropriate Azure AI config class for the given model.
+
+ Routes to specialized configs based on model type:
+ - Model Router: AzureModelRouterConfig
+ - Claude models: AzureAnthropicConfig
+ - Default: AzureAIStudioConfig
+
+ Args:
+ model: The model name
+
+ Returns:
+ The appropriate config instance
+ """
+ azure_ai_route = AzureFoundryModelInfo.get_azure_ai_route(model)
+
+ if azure_ai_route == "model_router":
+ from litellm.llms.azure_ai.azure_model_router.transformation import (
+ AzureModelRouterConfig,
+ )
+ return AzureModelRouterConfig()
+ elif "claude" in model.lower():
+ from litellm.llms.azure_ai.anthropic.transformation import (
+ AzureAnthropicConfig,
+ )
+ return AzureAnthropicConfig()
+ else:
+ from litellm.llms.azure_ai.chat.transformation import AzureAIStudioConfig
+ return AzureAIStudioConfig()
def validate_environment(
self,
diff --git a/litellm/llms/azure_ai/cost_calculator.py b/litellm/llms/azure_ai/cost_calculator.py
new file mode 100644
index 00000000000..999f94da182
--- /dev/null
+++ b/litellm/llms/azure_ai/cost_calculator.py
@@ -0,0 +1,121 @@
+"""
+Azure AI cost calculation helper.
+Handles Azure AI Foundry Model Router flat cost and other Azure AI specific pricing.
+"""
+
+from typing import Optional, Tuple
+
+from litellm._logging import verbose_logger
+from litellm.litellm_core_utils.llm_cost_calc.utils import generic_cost_per_token
+from litellm.types.utils import Usage
+from litellm.utils import get_model_info
+
+
+def _is_azure_model_router(model: str) -> bool:
+ """
+ Check if the model is Azure AI Foundry Model Router.
+
+ Detects patterns like:
+ - "azure-model-router"
+ - "model-router"
+ - "model_router/"
+ - "model-router/"
+
+ Args:
+ model: The model name
+
+ Returns:
+ bool: True if this is a model router model
+ """
+ model_lower = model.lower()
+ return (
+ "model-router" in model_lower
+ or "model_router" in model_lower
+ or model_lower == "azure-model-router"
+ )
+
+
+def calculate_azure_model_router_flat_cost(model: str, prompt_tokens: int) -> float:
+ """
+ Calculate the flat cost for Azure AI Foundry Model Router.
+
+ Args:
+ model: The model name (should be a model router model)
+ prompt_tokens: Number of prompt tokens
+
+ Returns:
+ float: The flat cost in USD, or 0.0 if not applicable
+ """
+ if not _is_azure_model_router(model):
+ return 0.0
+
+ # Get the model router pricing from model_prices_and_context_window.json
+ # Use "model_router" as the key (without actual model name suffix)
+ model_info = get_model_info(model="model_router", custom_llm_provider="azure_ai")
+ router_flat_cost_per_token = model_info.get("input_cost_per_token", 0)
+
+ if router_flat_cost_per_token > 0:
+ return prompt_tokens * router_flat_cost_per_token
+
+ return 0.0
+
+
+def cost_per_token(
+ model: str, usage: Usage, response_time_ms: Optional[float] = 0.0
+) -> Tuple[float, float]:
+ """
+ Calculate the cost per token for Azure AI models.
+
+ For Azure AI Foundry Model Router:
+ - Adds a flat cost of $0.14 per million input tokens (from model_prices_and_context_window.json)
+ - Plus the cost of the actual model used (handled by generic_cost_per_token)
+
+ Args:
+ model: str, the model name without provider prefix
+ usage: LiteLLM Usage block
+ response_time_ms: Optional response time in milliseconds
+
+ Returns:
+ Tuple[float, float] - prompt_cost_in_usd, completion_cost_in_usd
+
+ Raises:
+ ValueError: If the model is not found in the cost map and cost cannot be calculated
+ (except for Model Router models where we return just the routing flat cost)
+ """
+ prompt_cost = 0.0
+ completion_cost = 0.0
+
+ # Calculate base cost using generic cost calculator
+ # This may raise an exception if the model is not in the cost map
+ try:
+ prompt_cost, completion_cost = generic_cost_per_token(
+ model=model,
+ usage=usage,
+ custom_llm_provider="azure_ai",
+ )
+ except Exception as e:
+ # For Model Router, the model name (e.g., "azure-model-router") may not be in the cost map
+ # because it's a routing service, not an actual model. In this case, we continue
+ # to calculate just the routing flat cost.
+ if not _is_azure_model_router(model):
+ # Re-raise for non-router models - they should have pricing defined
+ raise
+ verbose_logger.debug(
+ f"Azure AI Model Router: model '{model}' not in cost map, calculating routing flat cost only. Error: {e}"
+ )
+
+ # Add flat cost for Azure Model Router
+ # The flat cost is defined in model_prices_and_context_window.json for azure_ai/model_router
+ if _is_azure_model_router(model):
+ router_flat_cost = calculate_azure_model_router_flat_cost(model, usage.prompt_tokens)
+
+ if router_flat_cost > 0:
+ verbose_logger.debug(
+ f"Azure AI Model Router flat cost: ${router_flat_cost:.6f} "
+ f"({usage.prompt_tokens} tokens × ${router_flat_cost / usage.prompt_tokens:.9f}/token)"
+ )
+
+ # Add flat cost to prompt cost
+ prompt_cost += router_flat_cost
+
+ return prompt_cost, completion_cost
diff --git a/litellm/llms/azure_ai/rerank/transformation.py b/litellm/llms/azure_ai/rerank/transformation.py
index a47b6082c37..f577a42ed58 100644
--- a/litellm/llms/azure_ai/rerank/transformation.py
+++ b/litellm/llms/azure_ai/rerank/transformation.py
@@ -11,6 +11,7 @@ from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLogging
from litellm.llms.cohere.rerank.transformation import CohereRerankConfig
from litellm.secret_managers.main import get_secret_str
from litellm.types.utils import RerankResponse
+from litellm.utils import _add_path_to_api_base
class AzureAIRerankConfig(CohereRerankConfig):
@@ -28,9 +29,34 @@ class AzureAIRerankConfig(CohereRerankConfig):
raise ValueError(
"Azure AI API Base is required. api_base=None. Set in call or via `AZURE_AI_API_BASE` env var."
)
- if not api_base.endswith("/v1/rerank"):
- api_base = f"{api_base}/v1/rerank"
- return api_base
+ original_url = httpx.URL(api_base)
+ if not original_url.is_absolute_url:
+ raise ValueError(
+ "Azure AI API Base must be an absolute URL including scheme (e.g. "
+ "'https://.services.ai.azure.com'). "
+ f"Got api_base={api_base!r}."
+ )
+ normalized_path = original_url.path.rstrip("/")
+
+ # Allow callers to pass either full v1/v2 rerank endpoints:
+ # - https://.services.ai.azure.com/v1/rerank
+ # - https://.services.ai.azure.com/providers/cohere/v2/rerank
+ if normalized_path.endswith("/v1/rerank") or normalized_path.endswith("/v2/rerank"):
+ return str(original_url.copy_with(path=normalized_path or "/"))
+
+ # If callers pass just the version path (e.g. ".../v2" or ".../providers/cohere/v2"), append "/rerank"
+ if (
+ normalized_path.endswith("/v1")
+ or normalized_path.endswith("/v2")
+ or normalized_path.endswith("/providers/cohere/v2")
+ ):
+ return _add_path_to_api_base(
+ api_base=str(original_url.copy_with(path=normalized_path or "/")),
+ ending_path="/rerank",
+ )
+
+ # Backwards compatible default: Azure AI rerank was originally exposed under /v1/rerank
+ return _add_path_to_api_base(api_base=api_base, ending_path="/v1/rerank")
def validate_environment(
self,
diff --git a/litellm/llms/base_llm/chat/transformation.py b/litellm/llms/base_llm/chat/transformation.py
index 41a1797cebe..ac209904e6e 100644
--- a/litellm/llms/base_llm/chat/transformation.py
+++ b/litellm/llms/base_llm/chat/transformation.py
@@ -437,3 +437,23 @@ class BaseConfig(ABC):
By default, this is true for almost all providers.
"""
return True
+
+ def calculate_additional_costs(
+ self, model: str, prompt_tokens: int, completion_tokens: int
+ ) -> Optional[dict]:
+ """
+ Calculate any additional costs beyond standard token costs.
+
+ This is used for provider-specific infrastructure costs, routing fees, etc.
+
+ Args:
+ model: The model name
+ prompt_tokens: Number of prompt tokens
+ completion_tokens: Number of completion tokens
+
+ Returns:
+ Optional dictionary with cost names and amounts, e.g.:
+ {"Infrastructure Fee": 0.001, "Routing Cost": 0.0005}
+ Returns None if no additional costs apply.
+ """
+ return None
diff --git a/litellm/llms/base_llm/vector_store/transformation.py b/litellm/llms/base_llm/vector_store/transformation.py
index 89f2094d5df..935fd53c199 100644
--- a/litellm/llms/base_llm/vector_store/transformation.py
+++ b/litellm/llms/base_llm/vector_store/transformation.py
@@ -5,8 +5,8 @@ import httpx
from litellm.types.router import GenericLiteLLMParams
from litellm.types.vector_stores import (
- BaseVectorStoreAuthCredentials,
VECTOR_STORE_OPENAI_PARAMS,
+ BaseVectorStoreAuthCredentials,
VectorStoreCreateOptionalRequestParams,
VectorStoreCreateResponse,
VectorStoreIndexEndpoints,
@@ -64,6 +64,30 @@ class BaseVectorStoreConfig:
pass
+ async def atransform_search_vector_store_request(
+ self,
+ vector_store_id: str,
+ query: Union[str, List[str]],
+ vector_store_search_optional_params: VectorStoreSearchOptionalRequestParams,
+ api_base: str,
+ litellm_logging_obj: LiteLLMLoggingObj,
+ litellm_params: dict,
+ ) -> Tuple[str, Dict]:
+ """
+ Optional async version of transform_search_vector_store_request.
+ If not implemented, the handler will fall back to the sync version.
+ Providers that need to make async calls (e.g., generating embeddings) should override this.
+ """
+ # Default implementation: call the sync version
+ return self.transform_search_vector_store_request(
+ vector_store_id=vector_store_id,
+ query=query,
+ vector_store_search_optional_params=vector_store_search_optional_params,
+ api_base=api_base,
+ litellm_logging_obj=litellm_logging_obj,
+ litellm_params=litellm_params,
+ )
+
@abstractmethod
def transform_search_vector_store_response(
self, response: httpx.Response, litellm_logging_obj: LiteLLMLoggingObj
diff --git a/litellm/llms/bedrock/base_aws_llm.py b/litellm/llms/bedrock/base_aws_llm.py
index 642d15fe3ed..1de1c40c438 100644
--- a/litellm/llms/bedrock/base_aws_llm.py
+++ b/litellm/llms/bedrock/base_aws_llm.py
@@ -1163,7 +1163,7 @@ class BaseAWSLLM:
def _sign_request(
self,
- service_name: Literal["bedrock", "sagemaker", "bedrock-agentcore"],
+ service_name: Literal["bedrock", "sagemaker", "bedrock-agentcore", "s3vectors"],
headers: dict,
optional_params: dict,
request_data: dict,
diff --git a/litellm/llms/bedrock/chat/converse_transformation.py b/litellm/llms/bedrock/chat/converse_transformation.py
index cb26a22edfa..7fc51263ebb 100644
--- a/litellm/llms/bedrock/chat/converse_transformation.py
+++ b/litellm/llms/bedrock/chat/converse_transformation.py
@@ -11,6 +11,9 @@ import httpx
import litellm
from litellm._logging import verbose_logger
+from litellm.anthropic_beta_headers_manager import (
+ filter_and_transform_beta_headers,
+)
from litellm.constants import RESPONSE_FORMAT_TOOL_NAME
from litellm.litellm_core_utils.core_helpers import (
filter_exceptions_from_params,
@@ -66,6 +69,7 @@ from ..common_utils import (
BedrockModelInfo,
get_anthropic_beta_from_headers,
get_bedrock_tool_name,
+ is_claude_4_5_on_bedrock,
)
# Computer use tool prefixes supported by Bedrock
@@ -76,6 +80,14 @@ BEDROCK_COMPUTER_USE_TOOLS = [
"text_editor_",
]
+# Beta header patterns that are not supported by Bedrock Converse API
+# These will be filtered out to prevent errors
+UNSUPPORTED_BEDROCK_CONVERSE_BETA_PATTERNS = [
+ "advanced-tool-use", # Bedrock Converse doesn't support advanced-tool-use beta headers
+ "prompt-caching", # Prompt caching not supported in Converse API
+ "compact-2026-01-12", # The compact beta feature is not currently supported on the Converse and ConverseStream APIs
+]
+
class AmazonConverseConfig(BaseConfig):
"""
@@ -298,6 +310,37 @@ class AmazonConverseConfig(BaseConfig):
# Check if the model is specifically Nova Lite 2
return "nova-2-lite" in model_without_region
+ def _map_web_search_options(
+ self, web_search_options: dict, model: str
+ ) -> Optional[BedrockToolBlock]:
+ """
+ Map web_search_options to Nova grounding systemTool.
+
+ Nova grounding (web search) is only supported on Amazon Nova models.
+ Returns None for non-Nova models.
+
+ Args:
+ web_search_options: The web_search_options dict from the request
+ model: The model identifier string
+
+ Returns:
+ BedrockToolBlock with systemTool for Nova models, None otherwise
+
+ Reference: https://docs.aws.amazon.com/nova/latest/userguide/grounding.html
+ """
+ # Only Nova models support nova_grounding
+ # Model strings can be like: "amazon.nova-pro-v1:0", "us.amazon.nova-pro-v1:0", etc.
+ if "nova" not in model.lower():
+ verbose_logger.debug(
+ f"web_search_options passed but model {model} is not a Nova model. "
+ "Nova grounding is only supported on Amazon Nova models."
+ )
+ return None
+
+ # Nova doesn't support search_context_size or user_location params
+ # (unlike Anthropic), so we just enable grounding with no options
+ return BedrockToolBlock(systemTool={"name": "nova_grounding"})
+
def _transform_reasoning_effort_to_reasoning_config(
self, reasoning_effort: str
) -> dict:
@@ -391,7 +434,7 @@ class AmazonConverseConfig(BaseConfig):
else:
# Anthropic and other models: convert to thinking parameter
optional_params["thinking"] = AnthropicConfig._map_reasoning_effort(
- reasoning_effort
+ reasoning_effort=reasoning_effort, model=model
)
def get_supported_openai_params(self, model: str) -> List[str]:
@@ -438,6 +481,10 @@ class AmazonConverseConfig(BaseConfig):
):
supported_params.append("tools")
+ # Nova models support web_search_options (mapped to nova_grounding systemTool)
+ if base_model.startswith("amazon.nova"):
+ supported_params.append("web_search_options")
+
if litellm.utils.supports_tool_choice(
model=model, custom_llm_provider=self.custom_llm_provider
) or litellm.utils.supports_tool_choice(
@@ -730,6 +777,15 @@ class AmazonConverseConfig(BaseConfig):
if bedrock_tier in ("default", "flex", "priority"):
optional_params["serviceTier"] = {"type": bedrock_tier}
+ if param == "web_search_options" and isinstance(value, dict):
+ # Note: we use `isinstance(value, dict)` instead of `value and isinstance(value, dict)`
+ # because empty dict {} is falsy but is a valid way to enable Nova grounding
+ grounding_tool = self._map_web_search_options(value, model)
+ if grounding_tool is not None:
+ optional_params = self._add_tools_to_optional_params(
+ optional_params=optional_params, tools=[grounding_tool]
+ )
+
# Only update thinking tokens for non-GPT-OSS models and non-Nova-Lite-2 models
# Nova Lite 2 handles token budgeting differently through reasoningConfig
if "gpt-oss" not in model and not self._is_nova_lite_2_model(model):
@@ -842,6 +898,7 @@ class AmazonConverseConfig(BaseConfig):
ChatCompletionAssistantMessage,
],
block_type: Literal["system"],
+ model: Optional[str] = None,
) -> Optional[SystemContentBlock]:
pass
@@ -855,6 +912,7 @@ class AmazonConverseConfig(BaseConfig):
ChatCompletionAssistantMessage,
],
block_type: Literal["content_block"],
+ model: Optional[str] = None,
) -> Optional[ContentBlock]:
pass
@@ -867,16 +925,26 @@ class AmazonConverseConfig(BaseConfig):
ChatCompletionAssistantMessage,
],
block_type: Literal["system", "content_block"],
+ model: Optional[str] = None,
) -> Optional[Union[SystemContentBlock, ContentBlock]]:
- if message_block.get("cache_control", None) is None:
+ cache_control = message_block.get("cache_control", None)
+ if cache_control is None:
return None
+
+ cache_point = CachePointBlock(type="default")
+ if isinstance(cache_control, dict) and "ttl" in cache_control:
+ ttl = cache_control["ttl"]
+ if ttl in ["5m", "1h"] and model is not None:
+ if is_claude_4_5_on_bedrock(model):
+ cache_point["ttl"] = ttl
+
if block_type == "system":
- return SystemContentBlock(cachePoint=CachePointBlock(type="default"))
+ return SystemContentBlock(cachePoint=cache_point)
else:
- return ContentBlock(cachePoint=CachePointBlock(type="default"))
+ return ContentBlock(cachePoint=cache_point)
def _transform_system_message(
- self, messages: List[AllMessageValues]
+ self, messages: List[AllMessageValues], model: Optional[str] = None
) -> Tuple[List[AllMessageValues], List[SystemContentBlock]]:
system_prompt_indices = []
system_content_blocks: List[SystemContentBlock] = []
@@ -888,7 +956,7 @@ class AmazonConverseConfig(BaseConfig):
SystemContentBlock(text=message["content"])
)
cache_block = self._get_cache_point_block(
- message, block_type="system"
+ message, block_type="system", model=model
)
if cache_block:
system_content_blocks.append(cache_block)
@@ -899,7 +967,7 @@ class AmazonConverseConfig(BaseConfig):
SystemContentBlock(text=m["text"])
)
cache_block = self._get_cache_point_block(
- m, block_type="system"
+ m, block_type="system", model=model
)
if cache_block:
system_content_blocks.append(cache_block)
@@ -997,10 +1065,16 @@ class AmazonConverseConfig(BaseConfig):
user_betas = get_anthropic_beta_from_headers(headers)
anthropic_beta_list.extend(user_betas)
- # Filter out tool search tools - Bedrock Converse API doesn't support them
+ # Separate pre-formatted Bedrock tools (e.g. systemTool from web_search_options)
+ # from OpenAI-format tools that need transformation via _bedrock_tools_pt
filtered_tools = []
+ pre_formatted_tools: List[ToolBlock] = []
if original_tools:
for tool in original_tools:
+ # Already-formatted Bedrock tools (e.g. systemTool for Nova grounding)
+ if "systemTool" in tool:
+ pre_formatted_tools.append(tool)
+ continue
tool_type = tool.get("type", "")
if tool_type in (
"tool_search_tool_regex_20251119",
@@ -1022,7 +1096,28 @@ class AmazonConverseConfig(BaseConfig):
# Add computer use tools and anthropic_beta if needed (only when computer use tools are present)
if computer_use_tools:
- anthropic_beta_list.append("computer-use-2024-10-22")
+ # Determine the correct computer-use beta header based on model
+ # "computer-use-2025-11-24" for Claude Opus 4.6, Claude Opus 4.5
+ # "computer-use-2025-01-24" for Claude Sonnet 4.5, Haiku 4.5, Opus 4.1, Sonnet 4, Opus 4, and Sonnet 3.7
+ # "computer-use-2024-10-22" for older models
+ model_lower = model.lower()
+ if "opus-4.6" in model_lower or "opus_4.6" in model_lower or "opus-4-6" in model_lower or "opus_4_6" in model_lower:
+ computer_use_header = "computer-use-2025-11-24"
+ elif "opus-4.5" in model_lower or "opus_4.5" in model_lower or "opus-4-5" in model_lower or "opus_4_5" in model_lower:
+ computer_use_header = "computer-use-2025-11-24"
+ elif any(pattern in model_lower for pattern in [
+ "sonnet-4.5", "sonnet_4.5", "sonnet-4-5", "sonnet_4_5",
+ "haiku-4.5", "haiku_4.5", "haiku-4-5", "haiku_4_5",
+ "opus-4.1", "opus_4.1", "opus-4-1", "opus_4_1",
+ "sonnet-4", "sonnet_4",
+ "opus-4", "opus_4",
+ "sonnet-3.7", "sonnet_3.7", "sonnet-3-7", "sonnet_3_7"
+ ]):
+ computer_use_header = "computer-use-2025-01-24"
+ else:
+ computer_use_header = "computer-use-2024-10-22"
+
+ anthropic_beta_list.append(computer_use_header)
# Transform computer use tools to proper Bedrock format
transformed_computer_tools = self._transform_computer_use_tools(
computer_use_tools
@@ -1032,6 +1127,9 @@ class AmazonConverseConfig(BaseConfig):
# No computer use tools, process all tools as regular tools
bedrock_tools = _bedrock_tools_pt(filtered_tools)
+ # Append pre-formatted tools (systemTool etc.) after transformation
+ bedrock_tools.extend(pre_formatted_tools)
+
# Set anthropic_beta in additional_request_params if we have any beta features
# ONLY apply to Anthropic/Claude models - other models (e.g., Qwen, Llama) don't support this field
# and will error with "unknown variant anthropic_beta" if included
@@ -1044,7 +1142,14 @@ class AmazonConverseConfig(BaseConfig):
if beta not in seen:
unique_betas.append(beta)
seen.add(beta)
- additional_request_params["anthropic_beta"] = unique_betas
+
+ filtered_betas = filter_and_transform_beta_headers(
+ beta_headers=unique_betas,
+ provider="bedrock_converse",
+ )
+
+ if filtered_betas:
+ additional_request_params["anthropic_beta"] = filtered_betas
return bedrock_tools, anthropic_beta_list
@@ -1096,9 +1201,11 @@ class AmazonConverseConfig(BaseConfig):
)
# Prepare and separate parameters
- inference_params, additional_request_params, request_metadata = self._prepare_request_params(
- optional_params, model
- )
+ (
+ inference_params,
+ additional_request_params,
+ request_metadata,
+ ) = self._prepare_request_params(optional_params, model)
original_tools = inference_params.pop("tools", [])
@@ -1150,7 +1257,9 @@ class AmazonConverseConfig(BaseConfig):
litellm_params: dict,
headers: Optional[dict] = None,
) -> RequestObject:
- messages, system_content_blocks = self._transform_system_message(messages)
+ messages, system_content_blocks = self._transform_system_message(
+ messages, model=model
+ )
# Convert last user message to guarded_text if guardrailConfig is present
messages = self._convert_consecutive_user_messages_to_guarded_text(
@@ -1206,7 +1315,9 @@ class AmazonConverseConfig(BaseConfig):
litellm_params: dict,
headers: Optional[dict] = None,
) -> RequestObject:
- messages, system_content_blocks = self._transform_system_message(messages)
+ messages, system_content_blocks = self._transform_system_message(
+ messages, model=model
+ )
# Convert last user message to guarded_text if guardrailConfig is present
messages = self._convert_consecutive_user_messages_to_guarded_text(
@@ -1384,24 +1495,29 @@ class AmazonConverseConfig(BaseConfig):
return message, returned_finish_reason
- def _translate_message_content(self, content_blocks: List[ContentBlock]) -> Tuple[
+ def _translate_message_content(
+ self, content_blocks: List[ContentBlock]
+ ) -> Tuple[
str,
List[ChatCompletionToolCallChunk],
Optional[List[BedrockConverseReasoningContentBlock]],
+ Optional[List[CitationsContentBlock]],
]:
"""
- Translate the message content to a string and a list of tool calls and reasoning content blocks
+ Translate the message content to a string and a list of tool calls, reasoning content blocks, and citations.
Returns:
content_str: str
tools: List[ChatCompletionToolCallChunk]
reasoningContentBlocks: Optional[List[BedrockConverseReasoningContentBlock]]
+ citationsContentBlocks: Optional[List[CitationsContentBlock]] - Citations from Nova grounding
"""
content_str = ""
tools: List[ChatCompletionToolCallChunk] = []
- reasoningContentBlocks: Optional[List[BedrockConverseReasoningContentBlock]] = (
- None
- )
+ reasoningContentBlocks: Optional[
+ List[BedrockConverseReasoningContentBlock]
+ ] = None
+ citationsContentBlocks: Optional[List[CitationsContentBlock]] = None
for idx, content in enumerate(content_blocks):
"""
- Content is either a tool response or text
@@ -1446,10 +1562,15 @@ class AmazonConverseConfig(BaseConfig):
if reasoningContentBlocks is None:
reasoningContentBlocks = []
reasoningContentBlocks.append(content["reasoningContent"])
+ # Handle Nova grounding citations content
+ if "citationsContent" in content:
+ if citationsContentBlocks is None:
+ citationsContentBlocks = []
+ citationsContentBlocks.append(content["citationsContent"])
- return content_str, tools, reasoningContentBlocks
+ return content_str, tools, reasoningContentBlocks, citationsContentBlocks
- def _transform_response(
+ def _transform_response( # noqa: PLR0915
self,
model: str,
response: httpx.Response,
@@ -1522,27 +1643,38 @@ class AmazonConverseConfig(BaseConfig):
chat_completion_message: ChatCompletionResponseMessage = {"role": "assistant"}
content_str = ""
tools: List[ChatCompletionToolCallChunk] = []
- reasoningContentBlocks: Optional[List[BedrockConverseReasoningContentBlock]] = (
- None
- )
+ reasoningContentBlocks: Optional[
+ List[BedrockConverseReasoningContentBlock]
+ ] = None
+ citationsContentBlocks: Optional[List[CitationsContentBlock]] = None
if message is not None:
(
content_str,
tools,
reasoningContentBlocks,
+ citationsContentBlocks,
) = self._translate_message_content(message["content"])
+ # Initialize provider_specific_fields if we have any special content blocks
+ provider_specific_fields: dict = {}
if reasoningContentBlocks is not None:
- chat_completion_message["provider_specific_fields"] = {
- "reasoningContentBlocks": reasoningContentBlocks,
- }
- chat_completion_message["reasoning_content"] = (
- self._transform_reasoning_content(reasoningContentBlocks)
- )
- chat_completion_message["thinking_blocks"] = (
- self._transform_thinking_blocks(reasoningContentBlocks)
- )
+ provider_specific_fields["reasoningContentBlocks"] = reasoningContentBlocks
+ if citationsContentBlocks is not None:
+ provider_specific_fields["citationsContent"] = citationsContentBlocks
+
+ if provider_specific_fields:
+ chat_completion_message[
+ "provider_specific_fields"
+ ] = provider_specific_fields
+
+ if reasoningContentBlocks is not None:
+ chat_completion_message[
+ "reasoning_content"
+ ] = self._transform_reasoning_content(reasoningContentBlocks)
+ chat_completion_message[
+ "thinking_blocks"
+ ] = self._transform_thinking_blocks(reasoningContentBlocks)
chat_completion_message["content"] = content_str
if (
json_mode is True
diff --git a/litellm/llms/bedrock/chat/invoke_handler.py b/litellm/llms/bedrock/chat/invoke_handler.py
index dfa1f02a155..1c58a11eebe 100644
--- a/litellm/llms/bedrock/chat/invoke_handler.py
+++ b/litellm/llms/bedrock/chat/invoke_handler.py
@@ -1476,6 +1476,11 @@ class AWSEventStreamDecoder:
reasoning_content = (
"" # set to non-empty string to ensure consistency with Anthropic
)
+ elif "citationsContent" in delta_obj:
+ # Handle Nova grounding citations in streaming responses
+ provider_specific_fields = {
+ "citationsContent": delta_obj["citationsContent"],
+ }
return (
text,
tool_use,
@@ -1527,7 +1532,7 @@ class AWSEventStreamDecoder:
]
] = None
- index = int(chunk_data.get("contentBlockIndex", 0))
+ content_block_index = int(chunk_data.get("contentBlockIndex", 0))
if "start" in chunk_data:
start_obj = ContentBlockStartEvent(**chunk_data["start"])
(
@@ -1543,11 +1548,11 @@ class AWSEventStreamDecoder:
provider_specific_fields,
reasoning_content,
thinking_blocks,
- ) = self._handle_converse_delta_event(delta_obj, index)
+ ) = self._handle_converse_delta_event(delta_obj, content_block_index)
elif (
"contentBlockIndex" in chunk_data
): # stop block, no 'start' or 'delta' object
- tool_use = self._handle_converse_stop_event(index)
+ tool_use = self._handle_converse_stop_event(content_block_index)
elif "stopReason" in chunk_data:
finish_reason = map_finish_reason(chunk_data.get("stopReason", "stop"))
elif "usage" in chunk_data:
@@ -1561,7 +1566,7 @@ class AWSEventStreamDecoder:
choices=[
StreamingChoices(
finish_reason=finish_reason,
- index=index,
+ index=0, # Always 0 - Bedrock never returns multiple choices
delta=Delta(
content=text,
role="assistant",
diff --git a/litellm/llms/bedrock/chat/invoke_transformations/anthropic_claude3_transformation.py b/litellm/llms/bedrock/chat/invoke_transformations/anthropic_claude3_transformation.py
index 53e08229799..c936b2cd23c 100644
--- a/litellm/llms/bedrock/chat/invoke_transformations/anthropic_claude3_transformation.py
+++ b/litellm/llms/bedrock/chat/invoke_transformations/anthropic_claude3_transformation.py
@@ -53,13 +53,26 @@ class AmazonAnthropicClaudeConfig(AmazonInvokeConfig, AnthropicConfig):
model: str,
drop_params: bool,
) -> dict:
- return AnthropicConfig.map_openai_params(
+ # Force tool-based structured outputs for Bedrock Invoke
+ # (similar to VertexAI fix in #19201)
+ # Bedrock Invoke doesn't support output_format parameter
+ original_model = model
+ if "response_format" in non_default_params:
+ # Use a model name that forces tool-based approach
+ model = "claude-3-sonnet-20240229"
+
+ optional_params = AnthropicConfig.map_openai_params(
self,
non_default_params,
optional_params,
model,
drop_params,
)
+
+ # Restore original model name
+ model = original_model
+
+ return optional_params
def transform_request(
@@ -90,6 +103,8 @@ class AmazonAnthropicClaudeConfig(AmazonInvokeConfig, AnthropicConfig):
_anthropic_request.pop("model", None)
_anthropic_request.pop("stream", None)
+ # Bedrock Invoke doesn't support output_format parameter
+ _anthropic_request.pop("output_format", None)
if "anthropic_version" not in _anthropic_request:
_anthropic_request["anthropic_version"] = self.anthropic_version
@@ -117,6 +132,26 @@ class AmazonAnthropicClaudeConfig(AmazonInvokeConfig, AnthropicConfig):
if "opus-4" in model.lower() or "opus_4" in model.lower():
beta_set.add("tool-search-tool-2025-10-19")
+ # Filter out beta headers that Bedrock Invoke doesn't support
+ # AWS Bedrock only supports a specific whitelist of beta flags
+ # Reference: https://docs.aws.amazon.com/bedrock/latest/userguide/model-parameters-anthropic-claude-messages-request-response.html
+ BEDROCK_SUPPORTED_BETAS = {
+ "computer-use-2024-10-22", # Legacy computer use
+ "computer-use-2025-01-24", # Current computer use (Claude 3.7 Sonnet)
+ "token-efficient-tools-2025-02-19", # Tool use (Claude 3.7+ and Claude 4+)
+ "interleaved-thinking-2025-05-14", # Interleaved thinking (Claude 4+)
+ "output-128k-2025-02-19", # 128K output tokens (Claude 3.7 Sonnet)
+ "dev-full-thinking-2025-05-14", # Developer mode for raw thinking (Claude 4+)
+ "context-1m-2025-08-07", # 1 million tokens (Claude Sonnet 4)
+ "context-management-2025-06-27", # Context management (Claude Sonnet/Haiku 4.5)
+ "effort-2025-11-24", # Effort parameter (Claude Opus 4.5)
+ "tool-search-tool-2025-10-19", # Tool search (Claude Opus 4.5)
+ "tool-examples-2025-10-29", # Tool use examples (Claude Opus 4.5)
+ }
+
+ # Only keep beta headers that Bedrock supports
+ beta_set = {beta for beta in beta_set if beta in BEDROCK_SUPPORTED_BETAS}
+
if beta_set:
_anthropic_request["anthropic_beta"] = list(beta_set)
diff --git a/litellm/llms/bedrock/common_utils.py b/litellm/llms/bedrock/common_utils.py
index 89b42f5e947..4c87f6fa994 100644
--- a/litellm/llms/bedrock/common_utils.py
+++ b/litellm/llms/bedrock/common_utils.py
@@ -446,6 +446,29 @@ def get_bedrock_base_model(model: str) -> str:
return model
+def is_claude_4_5_on_bedrock(model: str) -> bool:
+ """
+ Check if the model is a Claude 4.5 model on Bedrock.
+ Claude 4.5 models support prompt caching with '5m' and '1h' TTL on Bedrock.
+ """
+ model_lower = model.lower()
+ claude_4_5_patterns = [
+ "sonnet-4.5",
+ "sonnet_4.5",
+ "sonnet-4-5",
+ "sonnet_4_5",
+ "haiku-4.5",
+ "haiku_4.5",
+ "haiku-4-5",
+ "haiku_4_5",
+ "opus-4.5",
+ "opus_4.5",
+ "opus-4-5",
+ "opus_4_5",
+ ]
+ return any(pattern in model_lower for pattern in claude_4_5_patterns)
+
+
# Import after standalone functions to avoid circular imports
from litellm.llms.bedrock.count_tokens.bedrock_token_counter import BedrockTokenCounter
@@ -797,7 +820,7 @@ class BedrockEventStreamDecoderBase:
def get_anthropic_beta_from_headers(headers: dict) -> List[str]:
"""
Extract anthropic-beta header values and convert them to a list.
- Supports comma-separated values from user headers.
+ Supports both JSON array format and comma-separated values from user headers.
Used by both converse and invoke transformations for consistent handling
of anthropic-beta headers that should be passed to AWS Bedrock.
@@ -812,8 +835,27 @@ def get_anthropic_beta_from_headers(headers: dict) -> List[str]:
if not anthropic_beta_header:
return []
- # Split comma-separated values and strip whitespace
- return [beta.strip() for beta in anthropic_beta_header.split(",")]
+ # If it's already a list, return it
+ if isinstance(anthropic_beta_header, list):
+ return anthropic_beta_header
+
+ # Try to parse as JSON array first (e.g., '["interleaved-thinking-2025-05-14", "claude-code-20250219"]')
+ if isinstance(anthropic_beta_header, str):
+ anthropic_beta_header = anthropic_beta_header.strip()
+ if anthropic_beta_header.startswith("[") and anthropic_beta_header.endswith(
+ "]"
+ ):
+ try:
+ parsed = json.loads(anthropic_beta_header)
+ if isinstance(parsed, list):
+ return [str(beta).strip() for beta in parsed]
+ except json.JSONDecodeError:
+ pass # Fall through to comma-separated parsing
+
+ # Fall back to comma-separated values
+ return [beta.strip() for beta in anthropic_beta_header.split(",")]
+
+ return []
class CommonBatchFilesUtils:
diff --git a/litellm/llms/bedrock/embed/cohere_transformation.py b/litellm/llms/bedrock/embed/cohere_transformation.py
index 490cd71b793..d00cb74aae0 100644
--- a/litellm/llms/bedrock/embed/cohere_transformation.py
+++ b/litellm/llms/bedrock/embed/cohere_transformation.py
@@ -15,7 +15,7 @@ class BedrockCohereEmbeddingConfig:
pass
def get_supported_openai_params(self) -> List[str]:
- return ["encoding_format"]
+ return ["encoding_format", "dimensions"]
def map_openai_params(
self, non_default_params: dict, optional_params: dict
@@ -23,6 +23,8 @@ class BedrockCohereEmbeddingConfig:
for k, v in non_default_params.items():
if k == "encoding_format":
optional_params["embedding_types"] = v
+ elif k == "dimensions":
+ optional_params["output_dimension"] = v
return optional_params
def _is_v3_model(self, model: str) -> bool:
diff --git a/litellm/llms/bedrock/messages/invoke_transformations/anthropic_claude3_transformation.py b/litellm/llms/bedrock/messages/invoke_transformations/anthropic_claude3_transformation.py
index a7065caece2..19fe7d8c140 100644
--- a/litellm/llms/bedrock/messages/invoke_transformations/anthropic_claude3_transformation.py
+++ b/litellm/llms/bedrock/messages/invoke_transformations/anthropic_claude3_transformation.py
@@ -12,6 +12,9 @@ from typing import (
import httpx
+from litellm.anthropic_beta_headers_manager import (
+ filter_and_transform_beta_headers,
+)
from litellm.llms.anthropic.common_utils import AnthropicModelInfo
from litellm.llms.anthropic.experimental_pass_through.messages.transformation import (
AnthropicMessagesConfig,
@@ -23,7 +26,10 @@ from litellm.llms.bedrock.chat.invoke_handler import AWSEventStreamDecoder
from litellm.llms.bedrock.chat.invoke_transformations.base_invoke_transformation import (
AmazonInvokeConfig,
)
-from litellm.llms.bedrock.common_utils import get_anthropic_beta_from_headers
+from litellm.llms.bedrock.common_utils import (
+ get_anthropic_beta_from_headers,
+ is_claude_4_5_on_bedrock,
+)
from litellm.types.llms.anthropic import ANTHROPIC_TOOL_SEARCH_BETA_HEADER
from litellm.types.llms.openai import AllMessageValues
from litellm.types.router import GenericLiteLLMParams
@@ -52,9 +58,6 @@ class AmazonAnthropicClaudeMessagesConfig(
# Beta header patterns that are not supported by Bedrock Invoke API
# These will be filtered out to prevent 400 "invalid beta flag" errors
- UNSUPPORTED_BEDROCK_INVOKE_BETA_PATTERNS = [
- "advanced-tool-use", # Bedrock Invoke doesn't support advanced-tool-use beta headers
- ]
def __init__(self, **kwargs):
BaseAnthropicMessagesConfig.__init__(self, **kwargs)
@@ -115,15 +118,22 @@ class AmazonAnthropicClaudeMessagesConfig(
)
def _remove_ttl_from_cache_control(
- self, anthropic_messages_request: Dict
+ self, anthropic_messages_request: Dict, model: Optional[str] = None
) -> None:
"""
Remove `ttl` field from cache_control in messages.
Bedrock doesn't support the ttl field in cache_control.
+ Update: Bedock supports `5m` and `1h` for Claude 4.5 models.
+
Args:
anthropic_messages_request: The request dictionary to modify in-place
+ model: The model name to check if it supports ttl
"""
+ is_claude_4_5 = False
+ if model:
+ is_claude_4_5 = self._is_claude_4_5_on_bedrock(model)
+
if "messages" in anthropic_messages_request:
for message in anthropic_messages_request["messages"]:
if isinstance(message, dict) and "content" in message:
@@ -132,7 +142,14 @@ class AmazonAnthropicClaudeMessagesConfig(
for item in content:
if isinstance(item, dict) and "cache_control" in item:
cache_control = item["cache_control"]
- if isinstance(cache_control, dict) and "ttl" in cache_control:
+ if (
+ isinstance(cache_control, dict)
+ and "ttl" in cache_control
+ ):
+ ttl = cache_control["ttl"]
+ if is_claude_4_5 and ttl in ["5m", "1h"]:
+ continue
+
cache_control.pop("ttl", None)
def _supports_extended_thinking_on_bedrock(self, model: str) -> bool:
@@ -154,10 +171,84 @@ class AmazonAnthropicClaudeMessagesConfig(
# Supported models on Bedrock for extended thinking
supported_patterns = [
- "opus-4.5", "opus_4.5", "opus-4-5", "opus_4_5", # Opus 4.5
- "opus-4.1", "opus_4.1", "opus-4-1", "opus_4_1", # Opus 4.1
- "opus-4", "opus_4", # Opus 4
- "sonnet-4", "sonnet_4", # Sonnet 4
+ "opus-4.5",
+ "opus_4.5",
+ "opus-4-5",
+ "opus_4_5", # Opus 4.5
+ "opus-4.1",
+ "opus_4.1",
+ "opus-4-1",
+ "opus_4_1", # Opus 4.1
+ "opus-4",
+ "opus_4", # Opus 4
+ "sonnet-4",
+ "sonnet_4", # Sonnet 4
+ ]
+
+ return any(pattern in model_lower for pattern in supported_patterns)
+
+ def _is_claude_opus_4_5(self, model: str) -> bool:
+ """
+ Check if the model is Claude Opus 4.5.
+
+ Args:
+ model: The model name
+
+ Returns:
+ True if the model is Claude Opus 4.5
+ """
+ model_lower = model.lower()
+ opus_4_5_patterns = [
+ "opus-4.5",
+ "opus_4.5",
+ "opus-4-5",
+ "opus_4_5",
+ ]
+ return any(pattern in model_lower for pattern in opus_4_5_patterns)
+
+ def _is_claude_4_5_on_bedrock(self, model: str) -> bool:
+ """
+ Check if the model is Claude 4.5 on Bedrock.
+
+ Claude Sonnet 4.5, Haiku 4.5, and Opus 4.5 support 1-hour prompt caching.
+
+ Args:
+ model: The model name
+
+ Returns:
+ True if the model is Claude 4.5
+ """
+ return is_claude_4_5_on_bedrock(model)
+
+ def _supports_tool_search_on_bedrock(self, model: str) -> bool:
+ """
+ Check if the model supports tool search on Bedrock.
+
+ On Amazon Bedrock, server-side tool search is supported on Claude Opus 4.5
+ and Claude Sonnet 4.5 with the tool-search-tool-2025-10-19 beta header.
+
+ Ref: https://platform.claude.com/docs/en/agents-and-tools/tool-use/tool-search-tool
+
+ Args:
+ model: The model name
+
+ Returns:
+ True if the model supports tool search on Bedrock
+ """
+ model_lower = model.lower()
+
+ # Supported models for tool search on Bedrock
+ supported_patterns = [
+ # Opus 4.5
+ "opus-4.5",
+ "opus_4.5",
+ "opus-4-5",
+ "opus_4_5",
+ # Sonnet 4.5
+ "sonnet-4.5",
+ "sonnet_4.5",
+ "sonnet-4-5",
+ "sonnet_4_5",
]
return any(pattern in model_lower for pattern in supported_patterns)
@@ -169,40 +260,63 @@ class AmazonAnthropicClaudeMessagesConfig(
Remove beta headers that are not supported on Bedrock for the given model.
Extended thinking beta headers are only supported on specific Claude 4+ models.
- Advanced tool use headers are not supported on Bedrock Invoke API.
+ Advanced tool use headers are not supported on Bedrock Invoke API, but need to be
+ translated to Bedrock-specific headers for models that support tool search
+ (Claude Opus 4.5, Sonnet 4.5).
This prevents 400 "invalid beta flag" errors on Bedrock.
Note: Bedrock Invoke API fails with a 400 error when unsupported beta headers
are sent, returning: {"message":"invalid beta flag"}
+ Translation for models supporting tool search (Opus 4.5, Sonnet 4.5):
+ - advanced-tool-use-2025-11-20 -> tool-search-tool-2025-10-19 + tool-examples-2025-10-29
+
Args:
model: The model name
beta_set: The set of beta headers to filter in-place
"""
- beta_headers_to_remove = set()
-
- # 1. Filter out beta headers that are universally unsupported on Bedrock Invoke
- for beta in beta_set:
- for unsupported_pattern in self.UNSUPPORTED_BEDROCK_INVOKE_BETA_PATTERNS:
- if unsupported_pattern in beta.lower():
- beta_headers_to_remove.add(beta)
- break
-
- # 2. Filter out extended thinking headers for models that don't support them
+ # 1. Handle header transformations BEFORE filtering
+ # (advanced-tool-use -> tool-search-tool)
+ # This must happen before filtering because advanced-tool-use is in the unsupported list
+ has_advanced_tool_use = "advanced-tool-use-2025-11-20" in beta_set
+ if has_advanced_tool_use and self._supports_tool_search_on_bedrock(model):
+ beta_set.discard("advanced-tool-use-2025-11-20")
+ beta_set.add("tool-search-tool-2025-10-19")
+ beta_set.add("tool-examples-2025-10-29")
+
+ # 2. Apply provider-level filtering using centralized JSON config
+ beta_list = list(beta_set)
+ filtered_list = filter_and_transform_beta_headers(
+ beta_headers=beta_list,
+ provider="bedrock",
+ )
+
+ # Update the set with filtered headers
+ beta_set.clear()
+ beta_set.update(filtered_list)
+
+ # 2.1. Handle model-specific exceptions: structured-outputs is only supported on Opus 4.6
+ # Re-add structured-outputs if it was in the original set and model is Opus 4.6
+ model_lower = model.lower()
+ is_opus_4_6 = any(pattern in model_lower for pattern in ["opus-4.6", "opus_4.6", "opus-4-6", "opus_4_6"])
+ if is_opus_4_6 and "structured-outputs-2025-11-13" in beta_list:
+ beta_set.add("structured-outputs-2025-11-13")
+
+ # 3. Filter out extended thinking headers for models that don't support them
extended_thinking_patterns = [
"extended-thinking",
"interleaved-thinking",
]
if not self._supports_extended_thinking_on_bedrock(model):
+ beta_headers_to_remove = set()
for beta in beta_set:
for pattern in extended_thinking_patterns:
if pattern in beta.lower():
beta_headers_to_remove.add(beta)
break
-
- # Remove all filtered headers
- for beta in beta_headers_to_remove:
- beta_set.discard(beta)
+
+ for beta in beta_headers_to_remove:
+ beta_set.discard(beta)
def _get_tool_search_beta_header_for_bedrock(
self,
@@ -230,7 +344,9 @@ class AmazonAnthropicClaudeMessagesConfig(
input_examples_used: Whether input examples are used
beta_set: The set of beta headers to modify in-place
"""
- if tool_search_used and not (programmatic_tool_calling_used or input_examples_used):
+ if tool_search_used and not (
+ programmatic_tool_calling_used or input_examples_used
+ ):
beta_set.discard(ANTHROPIC_TOOL_SEARCH_BETA_HEADER)
if "opus-4" in model.lower() or "opus_4" in model.lower():
beta_set.add("tool-search-tool-2025-10-19")
@@ -242,13 +358,13 @@ class AmazonAnthropicClaudeMessagesConfig(
) -> None:
"""
Convert Anthropic output_format to inline schema in message content.
-
+
Bedrock Invoke doesn't support the output_format parameter, so we embed
the schema directly into the user message content as text instructions.
-
+
This approach adds the schema to the last user message, instructing the model
to respond in the specified JSON format.
-
+
Args:
output_format: The output_format dict with 'type' and 'schema'
anthropic_messages_request: The request dict to modify in-place
@@ -256,40 +372,37 @@ class AmazonAnthropicClaudeMessagesConfig(
Ref: https://aws.amazon.com/blogs/machine-learning/structured-data-response-with-amazon-bedrock-prompt-engineering-and-tool-use/
"""
import json
-
+
# Extract schema from output_format
schema = output_format.get("schema")
if not schema:
return
-
+
# Get messages from the request
messages = anthropic_messages_request.get("messages", [])
if not messages:
return
-
+
# Find the last user message
last_user_message_idx = None
for idx in range(len(messages) - 1, -1, -1):
if messages[idx].get("role") == "user":
last_user_message_idx = idx
break
-
+
if last_user_message_idx is None:
return
-
+
last_user_message = messages[last_user_message_idx]
content = last_user_message.get("content", [])
-
+
# Ensure content is a list
if isinstance(content, str):
content = [{"type": "text", "text": content}]
last_user_message["content"] = content
-
+
# Add schema as text content to the message
- schema_text = {
- "type": "text",
- "text": json.dumps(schema)
- }
+ schema_text = {"type": "text", "text": json.dumps(schema)}
content.append(schema_text)
def transform_anthropic_messages_request(
@@ -314,9 +427,9 @@ class AmazonAnthropicClaudeMessagesConfig(
# 1. anthropic_version is required for all claude models
if "anthropic_version" not in anthropic_messages_request:
- anthropic_messages_request["anthropic_version"] = (
- self.DEFAULT_BEDROCK_ANTHROPIC_API_VERSION
- )
+ anthropic_messages_request[
+ "anthropic_version"
+ ] = self.DEFAULT_BEDROCK_ANTHROPIC_API_VERSION
# 2. `stream` is not allowed in request body for bedrock invoke
if "stream" in anthropic_messages_request:
@@ -326,8 +439,10 @@ class AmazonAnthropicClaudeMessagesConfig(
if "model" in anthropic_messages_request:
anthropic_messages_request.pop("model", None)
- # 4. Remove `ttl` field from cache_control in messages (Bedrock doesn't support it)
- self._remove_ttl_from_cache_control(anthropic_messages_request)
+ # 4. Remove `ttl` field from cache_control in messages (Bedrock doesn't support it for older models)
+ self._remove_ttl_from_cache_control(
+ anthropic_messages_request=anthropic_messages_request, model=model
+ )
# 5. Convert `output_format` to inline schema (Bedrock invoke doesn't support output_format)
output_format = anthropic_messages_request.pop("output_format", None)
@@ -336,14 +451,14 @@ class AmazonAnthropicClaudeMessagesConfig(
output_format=output_format,
anthropic_messages_request=anthropic_messages_request,
)
-
+
# 6. AUTO-INJECT beta headers based on features used
anthropic_model_info = AnthropicModelInfo()
tools = anthropic_messages_optional_request_params.get("tools")
messages_typed = cast(List[AllMessageValues], messages)
tool_search_used = anthropic_model_info.is_tool_search_used(tools)
- programmatic_tool_calling_used = anthropic_model_info.is_programmatic_tool_calling_used(
- tools
+ programmatic_tool_calling_used = (
+ anthropic_model_info.is_programmatic_tool_calling_used(tools)
)
input_examples_used = anthropic_model_info.is_input_examples_used(tools)
@@ -376,8 +491,7 @@ class AmazonAnthropicClaudeMessagesConfig(
if beta_set:
anthropic_messages_request["anthropic_beta"] = list(beta_set)
-
-
+
return anthropic_messages_request
def get_async_streaming_response_iterator(
@@ -395,7 +509,7 @@ class AmazonAnthropicClaudeMessagesConfig(
)
# Convert decoded Bedrock events to Server-Sent Events expected by Anthropic clients.
return self.bedrock_sse_wrapper(
- completion_stream=completion_stream,
+ completion_stream=completion_stream,
litellm_logging_obj=litellm_logging_obj,
request_body=request_body,
)
@@ -414,14 +528,14 @@ class AmazonAnthropicClaudeMessagesConfig(
from litellm.llms.anthropic.experimental_pass_through.messages.streaming_iterator import (
BaseAnthropicMessagesStreamingIterator,
)
+
handler = BaseAnthropicMessagesStreamingIterator(
litellm_logging_obj=litellm_logging_obj,
request_body=request_body,
)
-
+
async for chunk in handler.async_sse_wrapper(completion_stream):
yield chunk
-
class AmazonAnthropicClaudeMessagesStreamDecoder(AWSEventStreamDecoder):
diff --git a/litellm/llms/bedrock/realtime/handler.py b/litellm/llms/bedrock/realtime/handler.py
new file mode 100644
index 00000000000..9b6a80f4a2f
--- /dev/null
+++ b/litellm/llms/bedrock/realtime/handler.py
@@ -0,0 +1,307 @@
+"""
+This file contains the handler for AWS Bedrock Nova Sonic realtime API.
+
+This uses aws_sdk_bedrock_runtime for bidirectional streaming with Nova Sonic.
+"""
+
+import asyncio
+import json
+from typing import Any, Optional
+
+from litellm._logging import verbose_proxy_logger
+from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLogging
+
+from ..base_aws_llm import BaseAWSLLM
+from .transformation import BedrockRealtimeConfig
+
+
+class BedrockRealtime(BaseAWSLLM):
+ """Handler for Bedrock Nova Sonic realtime speech-to-speech API."""
+
+ def __init__(self):
+ super().__init__()
+
+ async def async_realtime(
+ self,
+ model: str,
+ websocket: Any,
+ logging_obj: LiteLLMLogging,
+ api_base: Optional[str] = None,
+ api_key: Optional[str] = None,
+ timeout: Optional[float] = None,
+ aws_region_name: Optional[str] = None,
+ aws_access_key_id: Optional[str] = None,
+ aws_secret_access_key: Optional[str] = None,
+ aws_session_token: Optional[str] = None,
+ aws_role_name: Optional[str] = None,
+ aws_session_name: Optional[str] = None,
+ aws_profile_name: Optional[str] = None,
+ aws_web_identity_token: Optional[str] = None,
+ aws_sts_endpoint: Optional[str] = None,
+ aws_bedrock_runtime_endpoint: Optional[str] = None,
+ aws_external_id: Optional[str] = None,
+ **kwargs,
+ ):
+ """
+ Establish bidirectional streaming connection with Bedrock Nova Sonic.
+
+ Args:
+ model: Model ID (e.g., 'amazon.nova-sonic-v1:0')
+ websocket: Client WebSocket connection
+ logging_obj: LiteLLM logging object
+ aws_region_name: AWS region
+ Various AWS authentication parameters
+ """
+ try:
+ from aws_sdk_bedrock_runtime.client import (
+ BedrockRuntimeClient,
+ InvokeModelWithBidirectionalStreamOperationInput,
+ )
+ from aws_sdk_bedrock_runtime.config import Config
+ from smithy_aws_core.identity.environment import (
+ EnvironmentCredentialsResolver,
+ )
+ except ImportError:
+ raise ImportError(
+ "Missing aws_sdk_bedrock_runtime. Install with: pip install aws-sdk-bedrock-runtime"
+ )
+
+ # Get AWS region
+ if aws_region_name is None:
+ optional_params = {
+ "aws_region_name": aws_region_name,
+ }
+ aws_region_name = self._get_aws_region_name(optional_params, model)
+
+ # Get endpoint URL
+ if api_base is not None:
+ endpoint_uri = api_base
+ elif aws_bedrock_runtime_endpoint is not None:
+ endpoint_uri = aws_bedrock_runtime_endpoint
+ else:
+ endpoint_uri = f"https://bedrock-runtime.{aws_region_name}.amazonaws.com"
+
+ verbose_proxy_logger.debug(
+ f"Bedrock Realtime: Connecting to {endpoint_uri} with model {model}"
+ )
+
+ # Initialize Bedrock client with aws_sdk_bedrock_runtime
+ config = Config(
+ endpoint_uri=endpoint_uri,
+ region=aws_region_name,
+ aws_credentials_identity_resolver=EnvironmentCredentialsResolver(),
+ )
+ bedrock_client = BedrockRuntimeClient(config=config)
+
+ transformation_config = BedrockRealtimeConfig()
+
+ try:
+ # Initialize the bidirectional stream
+ bedrock_stream = await bedrock_client.invoke_model_with_bidirectional_stream(
+ InvokeModelWithBidirectionalStreamOperationInput(model_id=model)
+ )
+
+ verbose_proxy_logger.debug(
+ "Bedrock Realtime: Bidirectional stream established"
+ )
+
+ # Track state for transformation
+ session_state = {
+ "current_output_item_id": None,
+ "current_response_id": None,
+ "current_conversation_id": None,
+ "current_delta_chunks": None,
+ "current_item_chunks": None,
+ "current_delta_type": None,
+ "session_configuration_request": None,
+ }
+
+ # Create tasks for bidirectional forwarding
+ client_to_bedrock_task = asyncio.create_task(
+ self._forward_client_to_bedrock(
+ websocket,
+ bedrock_stream,
+ transformation_config,
+ model,
+ session_state,
+ )
+ )
+
+ bedrock_to_client_task = asyncio.create_task(
+ self._forward_bedrock_to_client(
+ bedrock_stream,
+ websocket,
+ transformation_config,
+ model,
+ logging_obj,
+ session_state,
+ )
+ )
+
+ # Wait for both tasks to complete
+ await asyncio.gather(
+ client_to_bedrock_task,
+ bedrock_to_client_task,
+ return_exceptions=True,
+ )
+
+ except Exception as e:
+ verbose_proxy_logger.exception(
+ f"Error in BedrockRealtime.async_realtime: {e}"
+ )
+ try:
+ await websocket.close(code=1011, reason=f"Internal error: {str(e)}")
+ except Exception:
+ pass
+ raise
+
+ async def _forward_client_to_bedrock(
+ self,
+ client_ws: Any,
+ bedrock_stream: Any,
+ transformation_config: BedrockRealtimeConfig,
+ model: str,
+ session_state: dict,
+ ):
+ """Forward messages from client WebSocket to Bedrock stream."""
+ try:
+ from aws_sdk_bedrock_runtime.models import (
+ BidirectionalInputPayloadPart,
+ InvokeModelWithBidirectionalStreamInputChunk,
+ )
+
+ while True:
+ # Receive message from client
+ message = await client_ws.receive_text()
+ verbose_proxy_logger.debug(
+ f"Bedrock Realtime: Received from client: {message[:200]}"
+ )
+
+ # Transform OpenAI format to Bedrock format
+ transformed_messages = transformation_config.transform_realtime_request(
+ message=message,
+ model=model,
+ session_configuration_request=session_state.get(
+ "session_configuration_request"
+ ),
+ )
+
+ # Send transformed messages to Bedrock
+ for bedrock_message in transformed_messages:
+ event = InvokeModelWithBidirectionalStreamInputChunk(
+ value=BidirectionalInputPayloadPart(
+ bytes_=bedrock_message.encode("utf-8")
+ )
+ )
+ await bedrock_stream.input_stream.send(event)
+ verbose_proxy_logger.debug(
+ f"Bedrock Realtime: Sent to Bedrock: {bedrock_message[:200]}"
+ )
+
+ except Exception as e:
+ verbose_proxy_logger.debug(
+ f"Client to Bedrock forwarding ended: {e}", exc_info=True
+ )
+ # Close the Bedrock stream input
+ try:
+ await bedrock_stream.input_stream.close()
+ except Exception:
+ pass
+
+ async def _forward_bedrock_to_client(
+ self,
+ bedrock_stream: Any,
+ client_ws: Any,
+ transformation_config: BedrockRealtimeConfig,
+ model: str,
+ logging_obj: LiteLLMLogging,
+ session_state: dict,
+ ):
+ """Forward messages from Bedrock stream to client WebSocket."""
+ try:
+ while True:
+ # Receive from Bedrock
+ output = await bedrock_stream.await_output()
+ result = await output[1].receive()
+
+ if result.value and result.value.bytes_:
+ bedrock_response = result.value.bytes_.decode("utf-8")
+ verbose_proxy_logger.debug(
+ f"Bedrock Realtime: Received from Bedrock: {bedrock_response[:200]}"
+ )
+
+ # Transform Bedrock format to OpenAI format
+ from litellm.types.realtime import RealtimeResponseTransformInput
+
+ realtime_response_transform_input: RealtimeResponseTransformInput = {
+ "current_output_item_id": session_state.get(
+ "current_output_item_id"
+ ),
+ "current_response_id": session_state.get("current_response_id"),
+ "current_conversation_id": session_state.get(
+ "current_conversation_id"
+ ),
+ "current_delta_chunks": session_state.get(
+ "current_delta_chunks"
+ ),
+ "current_item_chunks": session_state.get("current_item_chunks"),
+ "current_delta_type": session_state.get("current_delta_type"),
+ "session_configuration_request": session_state.get(
+ "session_configuration_request"
+ ),
+ }
+
+ transformed_response = (
+ transformation_config.transform_realtime_response(
+ message=bedrock_response,
+ model=model,
+ logging_obj=logging_obj,
+ realtime_response_transform_input=realtime_response_transform_input,
+ )
+ )
+
+ # Update session state
+ session_state.update(
+ {
+ "current_output_item_id": transformed_response.get(
+ "current_output_item_id"
+ ),
+ "current_response_id": transformed_response.get(
+ "current_response_id"
+ ),
+ "current_conversation_id": transformed_response.get(
+ "current_conversation_id"
+ ),
+ "current_delta_chunks": transformed_response.get(
+ "current_delta_chunks"
+ ),
+ "current_item_chunks": transformed_response.get(
+ "current_item_chunks"
+ ),
+ "current_delta_type": transformed_response.get(
+ "current_delta_type"
+ ),
+ "session_configuration_request": transformed_response.get(
+ "session_configuration_request"
+ ),
+ }
+ )
+
+ # Send transformed messages to client
+ openai_messages = transformed_response.get("response", [])
+ for openai_message in openai_messages:
+ message_json = json.dumps(openai_message)
+ await client_ws.send_text(message_json)
+ verbose_proxy_logger.debug(
+ f"Bedrock Realtime: Sent to client: {message_json[:200]}"
+ )
+
+ except Exception as e:
+ verbose_proxy_logger.debug(
+ f"Bedrock to client forwarding ended: {e}", exc_info=True
+ )
+ # Close the client WebSocket
+ try:
+ await client_ws.close()
+ except Exception:
+ pass
diff --git a/litellm/llms/bedrock/realtime/transformation.py b/litellm/llms/bedrock/realtime/transformation.py
new file mode 100644
index 00000000000..1dde1b47fe3
--- /dev/null
+++ b/litellm/llms/bedrock/realtime/transformation.py
@@ -0,0 +1,1156 @@
+"""
+This file contains the transformation logic for Bedrock Nova Sonic realtime API.
+
+Transforms between OpenAI Realtime API format and Bedrock Nova Sonic format.
+"""
+
+import json
+import uuid as uuid_lib
+from typing import Any, List, Optional, Union
+
+from litellm._logging import verbose_logger
+from litellm._uuid import uuid
+from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj
+from litellm.llms.base_llm.realtime.transformation import BaseRealtimeConfig
+from litellm.types.llms.openai import (
+ OpenAIRealtimeContentPartDone,
+ OpenAIRealtimeDoneEvent,
+ OpenAIRealtimeEvents,
+ OpenAIRealtimeOutputItemDone,
+ OpenAIRealtimeResponseAudioDone,
+ OpenAIRealtimeResponseContentPartAdded,
+ OpenAIRealtimeResponseDelta,
+ OpenAIRealtimeResponseDoneObject,
+ OpenAIRealtimeResponseTextDone,
+ OpenAIRealtimeStreamResponseBaseObject,
+ OpenAIRealtimeStreamResponseOutputItemAdded,
+ OpenAIRealtimeStreamSession,
+ OpenAIRealtimeStreamSessionEvents,
+)
+from litellm.types.realtime import (
+ ALL_DELTA_TYPES,
+ RealtimeResponseTransformInput,
+ RealtimeResponseTypedDict,
+)
+from litellm.utils import get_empty_usage
+
+
+class BedrockRealtimeConfig(BaseRealtimeConfig):
+ """Configuration for Bedrock Nova Sonic realtime transformations."""
+
+ def __init__(self):
+ # Track session state
+ self.prompt_name = str(uuid_lib.uuid4())
+ self.content_name = str(uuid_lib.uuid4())
+ self.audio_content_name = str(uuid_lib.uuid4())
+
+ # Default configuration values
+ # Inference configuration
+ self.max_tokens = 1024
+ self.top_p = 0.9
+ self.temperature = 0.7
+
+ # Audio output configuration
+ self.output_sample_rate_hertz = 24000
+ self.output_sample_size_bits = 16
+ self.output_channel_count = 1
+ self.voice_id = "matthew"
+ self.output_encoding = "base64"
+ self.output_audio_type = "SPEECH"
+ self.output_media_type = "audio/lpcm"
+
+ # Audio input configuration
+ self.input_sample_rate_hertz = 16000
+ self.input_sample_size_bits = 16
+ self.input_channel_count = 1
+ self.input_encoding = "base64"
+ self.input_audio_type = "SPEECH"
+ self.input_media_type = "audio/lpcm"
+
+ # Text configuration
+ self.text_media_type = "text/plain"
+
+ def validate_environment(
+ self, headers: dict, model: str, api_key: Optional[str] = None
+ ) -> dict:
+ """Validate environment - no special validation needed for Bedrock."""
+ return headers
+
+ def get_complete_url(
+ self, api_base: Optional[str], model: str, api_key: Optional[str] = None
+ ) -> str:
+ """Get complete URL - handled by aws_sdk_bedrock_runtime."""
+ return api_base or ""
+
+ def requires_session_configuration(self) -> bool:
+ """Bedrock requires session configuration."""
+ return True
+
+ def session_configuration_request(self, model: str, tools: Optional[List[dict]] = None) -> str:
+ """
+ Create initial session configuration for Bedrock Nova Sonic.
+
+ Args:
+ model: Model ID
+ tools: Optional list of tool definitions
+
+ Returns JSON string with session start and prompt start events.
+ """
+ session_start = {
+ "event": {
+ "sessionStart": {
+ "inferenceConfiguration": {
+ "maxTokens": self.max_tokens,
+ "topP": self.top_p,
+ "temperature": self.temperature,
+ }
+ }
+ }
+ }
+
+ prompt_start_config = {
+ "promptName": self.prompt_name,
+ "textOutputConfiguration": {"mediaType": self.text_media_type},
+ "audioOutputConfiguration": {
+ "mediaType": self.output_media_type,
+ "sampleRateHertz": self.output_sample_rate_hertz,
+ "sampleSizeBits": self.output_sample_size_bits,
+ "channelCount": self.output_channel_count,
+ "voiceId": self.voice_id,
+ "encoding": self.output_encoding,
+ "audioType": self.output_audio_type,
+ },
+ }
+
+ # Add tool configuration if tools are provided
+ if tools:
+ prompt_start_config["toolUseOutputConfiguration"] = {
+ "mediaType": "application/json"
+ }
+ prompt_start_config["toolConfiguration"] = {
+ "tools": self._transform_tools_to_bedrock_format(tools)
+ }
+
+ prompt_start = {"event": {"promptStart": prompt_start_config}}
+
+ # Return as a marker that we've sent the configuration
+ return json.dumps(
+ {"session_start": session_start, "prompt_start": prompt_start}
+ )
+
+ def _transform_tools_to_bedrock_format(self, tools: List[dict]) -> List[dict]:
+ """
+ Transform OpenAI tool format to Bedrock tool format.
+
+ Args:
+ tools: List of OpenAI format tools
+
+ Returns:
+ List of Bedrock format tools
+ """
+ bedrock_tools = []
+ for tool in tools:
+ if tool.get("type") == "function":
+ function = tool.get("function", {})
+ bedrock_tool = {
+ "toolSpec": {
+ "name": function.get("name", ""),
+ "description": function.get("description", ""),
+ "inputSchema": {
+ "json": json.dumps(function.get("parameters", {}))
+ }
+ }
+ }
+ bedrock_tools.append(bedrock_tool)
+ return bedrock_tools
+
+ def _map_audio_format_to_sample_rate(self, audio_format: str, is_output: bool = True) -> int:
+ """
+ Map OpenAI audio format to sample rate.
+
+ Args:
+ audio_format: OpenAI audio format (pcm16, g711_ulaw, g711_alaw)
+ is_output: Whether this is for output (True) or input (False)
+
+ Returns:
+ Sample rate in Hz
+ """
+ # OpenAI uses 24kHz for output and can vary for input
+ # Bedrock Nova Sonic uses 24kHz for output and 16kHz for input by default
+ if audio_format == "pcm16":
+ return 24000 if is_output else 16000
+ elif audio_format in ["g711_ulaw", "g711_alaw"]:
+ return 8000 # G.711 typically uses 8kHz
+ return 24000 if is_output else 16000
+
+ def transform_session_update_event(self, json_message: dict) -> List[str]:
+ """
+ Transform session.update event to Bedrock session configuration.
+
+ Args:
+ json_message: OpenAI session.update message
+
+ Returns:
+ List of Bedrock format messages (JSON strings)
+ """
+ verbose_logger.debug("Handling session.update")
+ messages: List[str] = []
+
+ session_config = json_message.get("session", {})
+
+ # Update inference configuration from session if provided
+ if "max_response_output_tokens" in session_config:
+ self.max_tokens = session_config["max_response_output_tokens"]
+ if "temperature" in session_config:
+ self.temperature = session_config["temperature"]
+
+ # Update audio output configuration from session if provided
+ if "voice" in session_config:
+ self.voice_id = session_config["voice"]
+ if "output_audio_format" in session_config:
+ output_format = session_config["output_audio_format"]
+ self.output_sample_rate_hertz = self._map_audio_format_to_sample_rate(
+ output_format, is_output=True
+ )
+
+ # Update audio input configuration from session if provided
+ if "input_audio_format" in session_config:
+ input_format = session_config["input_audio_format"]
+ self.input_sample_rate_hertz = self._map_audio_format_to_sample_rate(
+ input_format, is_output=False
+ )
+
+ # Allow direct override of sample rates if provided (custom extension)
+ if "output_sample_rate_hertz" in session_config:
+ self.output_sample_rate_hertz = session_config["output_sample_rate_hertz"]
+ if "input_sample_rate_hertz" in session_config:
+ self.input_sample_rate_hertz = session_config["input_sample_rate_hertz"]
+
+ # Send session start
+ session_start = {
+ "event": {
+ "sessionStart": {
+ "inferenceConfiguration": {
+ "maxTokens": self.max_tokens,
+ "topP": self.top_p,
+ "temperature": self.temperature,
+ }
+ }
+ }
+ }
+ messages.append(json.dumps(session_start))
+
+ # Send prompt start
+ prompt_start_config = {
+ "promptName": self.prompt_name,
+ "textOutputConfiguration": {"mediaType": self.text_media_type},
+ "audioOutputConfiguration": {
+ "mediaType": self.output_media_type,
+ "sampleRateHertz": self.output_sample_rate_hertz,
+ "sampleSizeBits": self.output_sample_size_bits,
+ "channelCount": self.output_channel_count,
+ "voiceId": self.voice_id,
+ "encoding": self.output_encoding,
+ "audioType": self.output_audio_type,
+ },
+ }
+
+ # Add tool configuration if tools are provided
+ tools = session_config.get("tools")
+ if tools:
+ prompt_start_config["toolUseOutputConfiguration"] = {
+ "mediaType": "application/json"
+ }
+ prompt_start_config["toolConfiguration"] = {
+ "tools": self._transform_tools_to_bedrock_format(tools)
+ }
+
+ prompt_start = {"event": {"promptStart": prompt_start_config}}
+ messages.append(json.dumps(prompt_start))
+
+ # Send system prompt if provided
+ instructions = session_config.get("instructions")
+ if instructions:
+ text_content_name = str(uuid_lib.uuid4())
+
+ # Content start
+ text_content_start = {
+ "event": {
+ "contentStart": {
+ "promptName": self.prompt_name,
+ "contentName": text_content_name,
+ "type": "TEXT",
+ "interactive": False,
+ "role": "SYSTEM",
+ "textInputConfiguration": {"mediaType": self.text_media_type},
+ }
+ }
+ }
+ messages.append(json.dumps(text_content_start))
+
+ # Text input
+ text_input = {
+ "event": {
+ "textInput": {
+ "promptName": self.prompt_name,
+ "contentName": text_content_name,
+ "content": instructions,
+ }
+ }
+ }
+ messages.append(json.dumps(text_input))
+
+ # Content end
+ text_content_end = {
+ "event": {
+ "contentEnd": {
+ "promptName": self.prompt_name,
+ "contentName": text_content_name,
+ }
+ }
+ }
+ messages.append(json.dumps(text_content_end))
+
+ return messages
+
+ def transform_input_audio_buffer_append_event(self, json_message: dict) -> List[str]:
+ """
+ Transform input_audio_buffer.append event to Bedrock audio input.
+
+ Args:
+ json_message: OpenAI input_audio_buffer.append message
+
+ Returns:
+ List of Bedrock format messages (JSON strings)
+ """
+ verbose_logger.debug("Handling input_audio_buffer.append")
+ messages: List[str] = []
+
+ # Check if we need to start audio content
+ if not hasattr(self, "_audio_content_started"):
+ audio_content_start = {
+ "event": {
+ "contentStart": {
+ "promptName": self.prompt_name,
+ "contentName": self.audio_content_name,
+ "type": "AUDIO",
+ "interactive": True,
+ "role": "USER",
+ "audioInputConfiguration": {
+ "mediaType": self.input_media_type,
+ "sampleRateHertz": self.input_sample_rate_hertz,
+ "sampleSizeBits": self.input_sample_size_bits,
+ "channelCount": self.input_channel_count,
+ "audioType": self.input_audio_type,
+ "encoding": self.input_encoding,
+ },
+ }
+ }
+ }
+ messages.append(json.dumps(audio_content_start))
+ self._audio_content_started = True
+
+ # Send audio chunk
+ audio_data = json_message.get("audio", "")
+ audio_event = {
+ "event": {
+ "audioInput": {
+ "promptName": self.prompt_name,
+ "contentName": self.audio_content_name,
+ "content": audio_data,
+ }
+ }
+ }
+ messages.append(json.dumps(audio_event))
+
+ return messages
+
+ def transform_input_audio_buffer_commit_event(self, json_message: dict) -> List[str]:
+ """
+ Transform input_audio_buffer.commit event to Bedrock audio content end.
+
+ Args:
+ json_message: OpenAI input_audio_buffer.commit message
+
+ Returns:
+ List of Bedrock format messages (JSON strings)
+ """
+ verbose_logger.debug("Handling input_audio_buffer.commit")
+ messages: List[str] = []
+
+ if hasattr(self, "_audio_content_started"):
+ audio_content_end = {
+ "event": {
+ "contentEnd": {
+ "promptName": self.prompt_name,
+ "contentName": self.audio_content_name,
+ }
+ }
+ }
+ messages.append(json.dumps(audio_content_end))
+ delattr(self, "_audio_content_started")
+
+ return messages
+
+ def transform_conversation_item_create_event(self, json_message: dict) -> List[str]:
+ """
+ Transform conversation.item.create event to Bedrock text input or tool result.
+
+ Args:
+ json_message: OpenAI conversation.item.create message
+
+ Returns:
+ List of Bedrock format messages (JSON strings)
+ """
+ verbose_logger.debug("Handling conversation.item.create")
+ messages: List[str] = []
+
+ item = json_message.get("item", {})
+ item_type = item.get("type")
+
+ # Handle tool result
+ if item_type == "function_call_output":
+ return self.transform_conversation_item_create_tool_result_event(json_message)
+
+ # Handle regular message
+ if item_type == "message":
+ content = item.get("content", [])
+ for content_part in content:
+ if content_part.get("type") == "input_text":
+ text_content_name = str(uuid_lib.uuid4())
+
+ # Content start
+ text_content_start = {
+ "event": {
+ "contentStart": {
+ "promptName": self.prompt_name,
+ "contentName": text_content_name,
+ "type": "TEXT",
+ "interactive": True,
+ "role": "USER",
+ "textInputConfiguration": {
+ "mediaType": self.text_media_type
+ },
+ }
+ }
+ }
+ messages.append(json.dumps(text_content_start))
+
+ # Text input
+ text_input = {
+ "event": {
+ "textInput": {
+ "promptName": self.prompt_name,
+ "contentName": text_content_name,
+ "content": content_part.get("text", ""),
+ }
+ }
+ }
+ messages.append(json.dumps(text_input))
+
+ # Content end
+ text_content_end = {
+ "event": {
+ "contentEnd": {
+ "promptName": self.prompt_name,
+ "contentName": text_content_name,
+ }
+ }
+ }
+ messages.append(json.dumps(text_content_end))
+
+ return messages
+
+ def transform_response_create_event(self, json_message: dict) -> List[str]:
+ """
+ Transform response.create event to Bedrock format.
+
+ Args:
+ json_message: OpenAI response.create message
+
+ Returns:
+ List of Bedrock format messages (JSON strings)
+ """
+ verbose_logger.debug("Handling response.create")
+ # Bedrock starts generating automatically, no explicit trigger needed
+ return []
+
+ def transform_response_cancel_event(self, json_message: dict) -> List[str]:
+ """
+ Transform response.cancel event to Bedrock format.
+
+ Args:
+ json_message: OpenAI response.cancel message
+
+ Returns:
+ List of Bedrock format messages (JSON strings)
+ """
+ verbose_logger.debug("Handling response.cancel")
+ # Send interrupt signal if needed
+ return []
+
+ def transform_realtime_request(
+ self,
+ message: str,
+ model: str,
+ session_configuration_request: Optional[str] = None,
+ ) -> List[str]:
+ """
+ Transform OpenAI realtime request to Bedrock Nova Sonic format.
+
+ Args:
+ message: OpenAI format message (JSON string)
+ model: Model ID
+ session_configuration_request: Previous session config
+
+ Returns:
+ List of Bedrock format messages (JSON strings)
+ """
+ try:
+ json_message = json.loads(message)
+ except json.JSONDecodeError:
+ verbose_logger.warning(f"Invalid JSON message: {message[:200]}")
+ return []
+
+ message_type = json_message.get("type")
+
+ # Route to appropriate transformation method
+ if message_type == "session.update":
+ return self.transform_session_update_event(json_message)
+ elif message_type == "input_audio_buffer.append":
+ return self.transform_input_audio_buffer_append_event(json_message)
+ elif message_type == "input_audio_buffer.commit":
+ return self.transform_input_audio_buffer_commit_event(json_message)
+ elif message_type == "conversation.item.create":
+ return self.transform_conversation_item_create_event(json_message)
+ elif message_type == "response.create":
+ return self.transform_response_create_event(json_message)
+ elif message_type == "response.cancel":
+ return self.transform_response_cancel_event(json_message)
+ else:
+ verbose_logger.warning(f"Unknown message type: {message_type}")
+ return []
+
+ def transform_session_start_event(
+ self,
+ event: dict,
+ model: str,
+ logging_obj: LiteLLMLoggingObj,
+ ) -> OpenAIRealtimeStreamSessionEvents:
+ """
+ Transform Bedrock sessionStart event to OpenAI session.created.
+
+ Args:
+ event: Bedrock sessionStart event
+ model: Model ID
+ logging_obj: Logging object
+
+ Returns:
+ OpenAI session.created event
+ """
+ verbose_logger.debug("Handling sessionStart")
+
+ session = OpenAIRealtimeStreamSession(
+ id=logging_obj.litellm_trace_id,
+ modalities=["text", "audio"],
+ )
+ if model is not None and isinstance(model, str):
+ session["model"] = model
+
+ return OpenAIRealtimeStreamSessionEvents(
+ type="session.created",
+ session=session,
+ event_id=str(uuid.uuid4()),
+ )
+
+ def transform_content_start_event(
+ self,
+ event: dict,
+ current_response_id: Optional[str],
+ current_output_item_id: Optional[str],
+ current_conversation_id: Optional[str],
+ ) -> tuple[
+ List[OpenAIRealtimeEvents],
+ Optional[str],
+ Optional[str],
+ Optional[str],
+ Optional[ALL_DELTA_TYPES],
+ ]:
+ """
+ Transform Bedrock contentStart event to OpenAI response events.
+
+ Args:
+ event: Bedrock contentStart event
+ current_response_id: Current response ID
+ current_output_item_id: Current output item ID
+ current_conversation_id: Current conversation ID
+
+ Returns:
+ Tuple of (events, response_id, output_item_id, conversation_id, delta_type)
+ """
+ content_start = event["contentStart"]
+ role = content_start.get("role")
+
+ if role != "ASSISTANT":
+ return [], current_response_id, current_output_item_id, current_conversation_id, None
+
+ verbose_logger.debug("Handling ASSISTANT contentStart")
+
+ # Initialize IDs if needed
+ if not current_response_id:
+ current_response_id = f"resp_{uuid.uuid4()}"
+ if not current_output_item_id:
+ current_output_item_id = f"item_{uuid.uuid4()}"
+ if not current_conversation_id:
+ current_conversation_id = f"conv_{uuid.uuid4()}"
+
+ # Determine content type
+ content_type = content_start.get("type", "TEXT")
+ current_delta_type: ALL_DELTA_TYPES = "text" if content_type == "TEXT" else "audio"
+
+ returned_messages: List[OpenAIRealtimeEvents] = []
+
+ # Send response.created
+ response_created = OpenAIRealtimeStreamResponseBaseObject(
+ type="response.created",
+ event_id=f"event_{uuid.uuid4()}",
+ response={
+ "object": "realtime.response",
+ "id": current_response_id,
+ "status": "in_progress",
+ "output": [],
+ "conversation_id": current_conversation_id,
+ },
+ )
+ returned_messages.append(response_created)
+
+ # Send response.output_item.added
+ output_item_added = OpenAIRealtimeStreamResponseOutputItemAdded(
+ type="response.output_item.added",
+ response_id=current_response_id,
+ output_index=0,
+ item={
+ "id": current_output_item_id,
+ "object": "realtime.item",
+ "type": "message",
+ "status": "in_progress",
+ "role": "assistant",
+ "content": [],
+ },
+ )
+ returned_messages.append(output_item_added)
+
+ # Send response.content_part.added
+ content_part_added = OpenAIRealtimeResponseContentPartAdded(
+ type="response.content_part.added",
+ content_index=0,
+ output_index=0,
+ event_id=f"event_{uuid.uuid4()}",
+ item_id=current_output_item_id,
+ part=(
+ {"type": "text", "text": ""}
+ if current_delta_type == "text"
+ else {"type": "audio", "transcript": ""}
+ ),
+ response_id=current_response_id,
+ )
+ returned_messages.append(content_part_added)
+
+ return (
+ returned_messages,
+ current_response_id,
+ current_output_item_id,
+ current_conversation_id,
+ current_delta_type,
+ )
+
+ def transform_text_output_event(
+ self,
+ event: dict,
+ current_output_item_id: Optional[str],
+ current_response_id: Optional[str],
+ current_delta_chunks: Optional[List[OpenAIRealtimeResponseDelta]],
+ ) -> tuple[List[OpenAIRealtimeEvents], Optional[List[OpenAIRealtimeResponseDelta]]]:
+ """
+ Transform Bedrock textOutput event to OpenAI response.text.delta.
+
+ Args:
+ event: Bedrock textOutput event
+ current_output_item_id: Current output item ID
+ current_response_id: Current response ID
+ current_delta_chunks: Current delta chunks
+
+ Returns:
+ Tuple of (events, updated_delta_chunks)
+ """
+ verbose_logger.debug("Handling textOutput")
+ text_content = event["textOutput"].get("content", "")
+
+ if not current_output_item_id or not current_response_id:
+ return [], current_delta_chunks
+
+ text_delta = OpenAIRealtimeResponseDelta(
+ type="response.text.delta",
+ content_index=0,
+ event_id=f"event_{uuid.uuid4()}",
+ item_id=current_output_item_id,
+ output_index=0,
+ response_id=current_response_id,
+ delta=text_content,
+ )
+
+ # Track delta chunks
+ if current_delta_chunks is None:
+ current_delta_chunks = []
+ current_delta_chunks.append(text_delta)
+
+ return [text_delta], current_delta_chunks
+
+ def transform_audio_output_event(
+ self,
+ event: dict,
+ current_output_item_id: Optional[str],
+ current_response_id: Optional[str],
+ ) -> List[OpenAIRealtimeEvents]:
+ """
+ Transform Bedrock audioOutput event to OpenAI response.audio.delta.
+
+ Args:
+ event: Bedrock audioOutput event
+ current_output_item_id: Current output item ID
+ current_response_id: Current response ID
+
+ Returns:
+ List of OpenAI events
+ """
+ verbose_logger.debug("Handling audioOutput")
+ audio_content = event["audioOutput"].get("content", "")
+
+ if not current_output_item_id or not current_response_id:
+ return []
+
+ audio_delta = OpenAIRealtimeResponseDelta(
+ type="response.audio.delta",
+ content_index=0,
+ event_id=f"event_{uuid.uuid4()}",
+ item_id=current_output_item_id,
+ output_index=0,
+ response_id=current_response_id,
+ delta=audio_content,
+ )
+
+ return [audio_delta]
+
+ def transform_content_end_event(
+ self,
+ event: dict,
+ current_output_item_id: Optional[str],
+ current_response_id: Optional[str],
+ current_delta_type: Optional[str],
+ current_delta_chunks: Optional[List[OpenAIRealtimeResponseDelta]],
+ ) -> tuple[List[OpenAIRealtimeEvents], Optional[List[OpenAIRealtimeResponseDelta]]]:
+ """
+ Transform Bedrock contentEnd event to OpenAI response done events.
+
+ Args:
+ event: Bedrock contentEnd event
+ current_output_item_id: Current output item ID
+ current_response_id: Current response ID
+ current_delta_type: Current delta type (text or audio)
+ current_delta_chunks: Current delta chunks
+
+ Returns:
+ Tuple of (events, reset_delta_chunks)
+ """
+ content_end = event["contentEnd"]
+ verbose_logger.debug(f"Handling contentEnd: {content_end}")
+
+ if not current_output_item_id or not current_response_id:
+ return [], current_delta_chunks
+
+ returned_messages: List[OpenAIRealtimeEvents] = []
+
+ # Send appropriate done event based on type
+ if current_delta_type == "text":
+ # Accumulate text
+ accumulated_text = ""
+ if current_delta_chunks:
+ accumulated_text = "".join(
+ [chunk.get("delta", "") for chunk in current_delta_chunks]
+ )
+
+ text_done = OpenAIRealtimeResponseTextDone(
+ type="response.text.done",
+ content_index=0,
+ event_id=f"event_{uuid.uuid4()}",
+ item_id=current_output_item_id,
+ output_index=0,
+ response_id=current_response_id,
+ text=accumulated_text,
+ )
+ returned_messages.append(text_done)
+
+ # Send content_part.done
+ content_part_done = OpenAIRealtimeContentPartDone(
+ type="response.content_part.done",
+ content_index=0,
+ event_id=f"event_{uuid.uuid4()}",
+ item_id=current_output_item_id,
+ output_index=0,
+ part={"type": "text", "text": accumulated_text},
+ response_id=current_response_id,
+ )
+ returned_messages.append(content_part_done)
+
+ elif current_delta_type == "audio":
+ audio_done = OpenAIRealtimeResponseAudioDone(
+ type="response.audio.done",
+ content_index=0,
+ event_id=f"event_{uuid.uuid4()}",
+ item_id=current_output_item_id,
+ output_index=0,
+ response_id=current_response_id,
+ )
+ returned_messages.append(audio_done)
+
+ # Send content_part.done
+ content_part_done = OpenAIRealtimeContentPartDone(
+ type="response.content_part.done",
+ content_index=0,
+ event_id=f"event_{uuid.uuid4()}",
+ item_id=current_output_item_id,
+ output_index=0,
+ part={"type": "audio", "transcript": ""},
+ response_id=current_response_id,
+ )
+ returned_messages.append(content_part_done)
+
+ # Send output_item.done
+ output_item_done = OpenAIRealtimeOutputItemDone(
+ type="response.output_item.done",
+ event_id=f"event_{uuid.uuid4()}",
+ output_index=0,
+ response_id=current_response_id,
+ item={
+ "id": current_output_item_id,
+ "object": "realtime.item",
+ "type": "message",
+ "status": "completed",
+ "role": "assistant",
+ "content": [],
+ },
+ )
+ returned_messages.append(output_item_done)
+
+ # Reset delta chunks
+ return returned_messages, None
+
+ def transform_prompt_end_event(
+ self,
+ event: dict,
+ current_response_id: Optional[str],
+ current_conversation_id: Optional[str],
+ ) -> tuple[List[OpenAIRealtimeEvents], Optional[str], Optional[str], Optional[ALL_DELTA_TYPES]]:
+ """
+ Transform Bedrock promptEnd event to OpenAI response.done.
+
+ Args:
+ event: Bedrock promptEnd event
+ current_response_id: Current response ID
+ current_conversation_id: Current conversation ID
+
+ Returns:
+ Tuple of (events, reset_output_item_id, reset_response_id, reset_delta_type)
+ """
+ verbose_logger.debug("Handling promptEnd")
+
+ if not current_response_id or not current_conversation_id:
+ return [], None, None, None
+
+ usage_obj = get_empty_usage()
+ response_done = OpenAIRealtimeDoneEvent(
+ type="response.done",
+ event_id=f"event_{uuid.uuid4()}",
+ response=OpenAIRealtimeResponseDoneObject(
+ object="realtime.response",
+ id=current_response_id,
+ status="completed",
+ output=[],
+ conversation_id=current_conversation_id,
+ usage={
+ "prompt_tokens": usage_obj.prompt_tokens,
+ "completion_tokens": usage_obj.completion_tokens,
+ "total_tokens": usage_obj.total_tokens,
+ },
+ ),
+ )
+
+ # Reset state for next response
+ return [response_done], None, None, None
+
+ def transform_tool_use_event(
+ self,
+ event: dict,
+ current_output_item_id: Optional[str],
+ current_response_id: Optional[str],
+ ) -> tuple[List[OpenAIRealtimeEvents], str, str]:
+ """
+ Transform Bedrock toolUse event to OpenAI format.
+
+ Args:
+ event: Bedrock toolUse event
+ current_output_item_id: Current output item ID
+ current_response_id: Current response ID
+
+ Returns:
+ Tuple of (events, tool_call_id, tool_name) for tracking
+ """
+ verbose_logger.debug("Handling toolUse")
+ tool_use = event["toolUse"]
+
+ if not current_output_item_id or not current_response_id:
+ return [], "", ""
+
+ # Parse the tool input
+ tool_input = {}
+ if "input" in tool_use:
+ try:
+ tool_input = json.loads(tool_use["input"]) if isinstance(tool_use["input"], str) else tool_use["input"]
+ except json.JSONDecodeError:
+ tool_input = {}
+
+ tool_call_id = tool_use.get("toolUseId", "")
+ tool_name = tool_use.get("toolName", "")
+
+ # Create a function call arguments done event
+ # This is a custom event format that matches what clients expect
+ from typing import cast
+ function_call_event: dict[str, Any] = {
+ "type": "response.function_call_arguments.done",
+ "event_id": f"event_{uuid.uuid4()}",
+ "response_id": current_response_id,
+ "item_id": current_output_item_id,
+ "output_index": 0,
+ "call_id": tool_call_id,
+ "name": tool_name,
+ "arguments": json.dumps(tool_input),
+ }
+
+ return [cast(OpenAIRealtimeEvents, function_call_event)], tool_call_id, tool_name
+
+ def transform_conversation_item_create_tool_result_event(self, json_message: dict) -> List[str]:
+ """
+ Transform conversation.item.create with tool result to Bedrock format.
+
+ Args:
+ json_message: OpenAI conversation.item.create message with tool result
+
+ Returns:
+ List of Bedrock format messages (JSON strings)
+ """
+ verbose_logger.debug("Handling conversation.item.create for tool result")
+ messages: List[str] = []
+
+ item = json_message.get("item", {})
+ if item.get("type") == "function_call_output":
+ tool_content_name = str(uuid_lib.uuid4())
+ call_id = item.get("call_id", "")
+ output = item.get("output", "")
+
+ # Content start for tool result
+ tool_content_start = {
+ "event": {
+ "contentStart": {
+ "promptName": self.prompt_name,
+ "contentName": tool_content_name,
+ "interactive": False,
+ "type": "TOOL",
+ "role": "TOOL",
+ "toolResultInputConfiguration": {
+ "toolUseId": call_id,
+ "type": "TEXT",
+ "textInputConfiguration": {
+ "mediaType": "text/plain"
+ }
+ }
+ }
+ }
+ }
+ messages.append(json.dumps(tool_content_start))
+
+ # Tool result
+ tool_result = {
+ "event": {
+ "toolResult": {
+ "promptName": self.prompt_name,
+ "contentName": tool_content_name,
+ "content": output if isinstance(output, str) else json.dumps(output)
+ }
+ }
+ }
+ messages.append(json.dumps(tool_result))
+
+ # Content end
+ tool_content_end = {
+ "event": {
+ "contentEnd": {
+ "promptName": self.prompt_name,
+ "contentName": tool_content_name,
+ }
+ }
+ }
+ messages.append(json.dumps(tool_content_end))
+
+ return messages
+
+ def transform_realtime_response(
+ self,
+ message: Union[str, bytes],
+ model: str,
+ logging_obj: LiteLLMLoggingObj,
+ realtime_response_transform_input: RealtimeResponseTransformInput,
+ ) -> RealtimeResponseTypedDict:
+ """
+ Transform Bedrock Nova Sonic response to OpenAI realtime format.
+
+ Args:
+ message: Bedrock format message (JSON string)
+ model: Model ID
+ logging_obj: Logging object
+ realtime_response_transform_input: Current state
+
+ Returns:
+ Transformed response with updated state
+ """
+ try:
+ json_message = json.loads(message)
+ except json.JSONDecodeError:
+ message_preview = message[:200].decode('utf-8', errors='replace') if isinstance(message, bytes) else message[:200]
+ verbose_logger.warning(f"Invalid JSON message: {message_preview}")
+ return {
+ "response": [],
+ "current_output_item_id": realtime_response_transform_input.get(
+ "current_output_item_id"
+ ),
+ "current_response_id": realtime_response_transform_input.get(
+ "current_response_id"
+ ),
+ "current_delta_chunks": realtime_response_transform_input.get(
+ "current_delta_chunks"
+ ),
+ "current_conversation_id": realtime_response_transform_input.get(
+ "current_conversation_id"
+ ),
+ "current_item_chunks": realtime_response_transform_input.get(
+ "current_item_chunks"
+ ),
+ "current_delta_type": realtime_response_transform_input.get(
+ "current_delta_type"
+ ),
+ "session_configuration_request": realtime_response_transform_input.get(
+ "session_configuration_request"
+ ),
+ }
+
+ # Extract state
+ current_output_item_id = realtime_response_transform_input.get(
+ "current_output_item_id"
+ )
+ current_response_id = realtime_response_transform_input.get(
+ "current_response_id"
+ )
+ current_conversation_id = realtime_response_transform_input.get(
+ "current_conversation_id"
+ )
+ current_delta_chunks = realtime_response_transform_input.get(
+ "current_delta_chunks"
+ )
+ current_delta_type = realtime_response_transform_input.get("current_delta_type")
+ session_configuration_request = realtime_response_transform_input.get(
+ "session_configuration_request"
+ )
+
+ returned_messages: List[OpenAIRealtimeEvents] = []
+
+ # Parse Bedrock event
+ event = json_message.get("event", {})
+
+ # Route to appropriate transformation method
+ if "sessionStart" in event:
+ session_created = self.transform_session_start_event(
+ event, model, logging_obj
+ )
+ returned_messages.append(session_created)
+ session_configuration_request = json.dumps({"configured": True})
+
+ elif "contentStart" in event:
+ (
+ events,
+ current_response_id,
+ current_output_item_id,
+ current_conversation_id,
+ current_delta_type,
+ ) = self.transform_content_start_event(
+ event,
+ current_response_id,
+ current_output_item_id,
+ current_conversation_id,
+ )
+ returned_messages.extend(events)
+
+ elif "textOutput" in event:
+ events, current_delta_chunks = self.transform_text_output_event(
+ event,
+ current_output_item_id,
+ current_response_id,
+ current_delta_chunks,
+ )
+ returned_messages.extend(events)
+
+ elif "audioOutput" in event:
+ events = self.transform_audio_output_event(
+ event, current_output_item_id, current_response_id
+ )
+ returned_messages.extend(events)
+
+ elif "contentEnd" in event:
+ events, current_delta_chunks = self.transform_content_end_event(
+ event,
+ current_output_item_id,
+ current_response_id,
+ current_delta_type,
+ current_delta_chunks,
+ )
+ returned_messages.extend(events)
+
+ elif "toolUse" in event:
+ events, tool_call_id, tool_name = self.transform_tool_use_event(
+ event, current_output_item_id, current_response_id
+ )
+ returned_messages.extend(events)
+ # Store tool call info for potential use
+ verbose_logger.debug(f"Tool use event: {tool_name} (ID: {tool_call_id})")
+
+ elif "promptEnd" in event:
+ (
+ events,
+ current_output_item_id,
+ current_response_id,
+ current_delta_type,
+ ) = self.transform_prompt_end_event(
+ event, current_response_id, current_conversation_id
+ )
+ returned_messages.extend(events)
+
+ return {
+ "response": returned_messages,
+ "current_output_item_id": current_output_item_id,
+ "current_response_id": current_response_id,
+ "current_delta_chunks": current_delta_chunks,
+ "current_conversation_id": current_conversation_id,
+ "current_item_chunks": realtime_response_transform_input.get(
+ "current_item_chunks"
+ ),
+ "current_delta_type": current_delta_type,
+ "session_configuration_request": session_configuration_request,
+ }
diff --git a/litellm/llms/cerebras/chat.py b/litellm/llms/cerebras/chat.py
index 4e9c6811a77..9929e2ab9a2 100644
--- a/litellm/llms/cerebras/chat.py
+++ b/litellm/llms/cerebras/chat.py
@@ -7,6 +7,7 @@ this is OpenAI compatible - no translation needed / occurs
from typing import Optional
from litellm.llms.openai.chat.gpt_transformation import OpenAIGPTConfig
+from litellm.utils import supports_reasoning
class CerebrasConfig(OpenAIGPTConfig):
@@ -24,6 +25,7 @@ class CerebrasConfig(OpenAIGPTConfig):
tool_choice: Optional[str] = None
tools: Optional[list] = None
user: Optional[str] = None
+ reasoning_effort: Optional[str] = None
def __init__(
self,
@@ -37,6 +39,7 @@ class CerebrasConfig(OpenAIGPTConfig):
tool_choice: Optional[str] = None,
tools: Optional[list] = None,
user: Optional[str] = None,
+ reasoning_effort: Optional[str] = None,
) -> None:
locals_ = locals().copy()
for key, value in locals_.items():
@@ -53,7 +56,7 @@ class CerebrasConfig(OpenAIGPTConfig):
"""
- return [
+ supported_params = [
"max_tokens",
"max_completion_tokens",
"response_format",
@@ -67,6 +70,12 @@ class CerebrasConfig(OpenAIGPTConfig):
"user",
]
+ # Only add reasoning_effort for models that support it
+ if supports_reasoning(model=model, custom_llm_provider="cerebras"):
+ supported_params.append("reasoning_effort")
+
+ return supported_params
+
def map_openai_params(
self,
non_default_params: dict,
diff --git a/litellm/llms/cohere/rerank/guardrail_translation/handler.py b/litellm/llms/cohere/rerank/guardrail_translation/handler.py
index 6893a5991c3..b8133c59f7d 100644
--- a/litellm/llms/cohere/rerank/guardrail_translation/handler.py
+++ b/litellm/llms/cohere/rerank/guardrail_translation/handler.py
@@ -9,6 +9,7 @@ from typing import TYPE_CHECKING, Any, Optional
from litellm._logging import verbose_proxy_logger
from litellm.llms.base_llm.guardrail_translation.base_translation import BaseTranslation
+from litellm.types.utils import GenericGuardrailAPIInputs
if TYPE_CHECKING:
from litellm.integrations.custom_guardrail import CustomGuardrail
@@ -49,8 +50,13 @@ class CohereRerankHandler(BaseTranslation):
# Process query only
query = data.get("query")
if query is not None and isinstance(query, str):
+ inputs = GenericGuardrailAPIInputs(texts=[query])
+ # Include model information if available
+ model = data.get("model")
+ if model:
+ inputs["model"] = model
guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
- inputs={"texts": [query]},
+ inputs=inputs,
request_data=data,
input_type="request",
logging_obj=litellm_logging_obj,
diff --git a/litellm/llms/custom_httpx/http_handler.py b/litellm/llms/custom_httpx/http_handler.py
index 4f86877a6c0..ac9dd5998e2 100644
--- a/litellm/llms/custom_httpx/http_handler.py
+++ b/litellm/llms/custom_httpx/http_handler.py
@@ -50,9 +50,21 @@ try:
except Exception:
version = "0.0.0"
-headers = {
- "User-Agent": f"litellm/{version}",
-}
+def get_default_headers() -> dict:
+ """
+ Get default headers for HTTP requests.
+
+ - Default: `User-Agent: litellm/{version}`
+ - Override: set `LITELLM_USER_AGENT` to fully override the header value.
+ """
+ user_agent = os.environ.get("LITELLM_USER_AGENT")
+ if user_agent is not None:
+ return {"User-Agent": user_agent}
+
+ return {"User-Agent": f"litellm/{version}"}
+
+# Initialize headers (User-Agent)
+headers = get_default_headers()
# https://www.python-httpx.org/advanced/timeouts
_DEFAULT_TIMEOUT = httpx.Timeout(timeout=5.0, connect=5.0)
@@ -371,13 +383,16 @@ class AsyncHTTPHandler:
shared_session=shared_session,
)
+ # Get default headers (User-Agent, overridable via LITELLM_USER_AGENT)
+ default_headers = get_default_headers()
+
return httpx.AsyncClient(
transport=transport,
event_hooks=event_hooks,
timeout=timeout,
verify=ssl_config,
cert=cert,
- headers=headers,
+ headers=default_headers,
follow_redirects=True,
)
@@ -899,6 +914,9 @@ class HTTPHandler:
# /path/to/client.pem
cert = os.getenv("SSL_CERTIFICATE", litellm.ssl_certificate)
+ # Get default headers (User-Agent, overridable via LITELLM_USER_AGENT)
+ default_headers = get_default_headers() if not disable_default_headers else None
+
if client is None:
transport = self._create_sync_transport()
@@ -908,7 +926,7 @@ class HTTPHandler:
timeout=timeout,
verify=ssl_config,
cert=cert,
- headers=headers if not disable_default_headers else None,
+ headers=default_headers,
follow_redirects=True,
)
else:
diff --git a/litellm/llms/custom_httpx/httpx_handler.py b/litellm/llms/custom_httpx/httpx_handler.py
index 6f684ba01c2..491cd97f7db 100644
--- a/litellm/llms/custom_httpx/httpx_handler.py
+++ b/litellm/llms/custom_httpx/httpx_handler.py
@@ -1,3 +1,4 @@
+import os
from typing import Optional, Union
import httpx
@@ -7,13 +8,22 @@ try:
except Exception:
version = "0.0.0"
-headers = {
- "User-Agent": f"litellm/{version}",
-}
+def get_default_headers() -> dict:
+ """
+ Get default headers for HTTP requests.
+ - Default: `User-Agent: litellm/{version}`
+ - Override: set `LITELLM_USER_AGENT` to fully override the header value.
+ """
+ user_agent = os.environ.get("LITELLM_USER_AGENT")
+ if user_agent is not None:
+ return {"User-Agent": user_agent}
+
+ return {"User-Agent": f"litellm/{version}"}
class HTTPHandler:
def __init__(self, concurrent_limit=1000):
+ headers = get_default_headers()
# Create a client with a connection pool
self.client = httpx.AsyncClient(
limits=httpx.Limits(
diff --git a/litellm/llms/custom_httpx/llm_http_handler.py b/litellm/llms/custom_httpx/llm_http_handler.py
index 6a87967c3aa..d2ea7e872a2 100644
--- a/litellm/llms/custom_httpx/llm_http_handler.py
+++ b/litellm/llms/custom_httpx/llm_http_handler.py
@@ -7033,17 +7033,31 @@ class BaseLLMHTTPHandler:
litellm_params=dict(litellm_params),
)
- (
- url,
- request_body,
- ) = vector_store_provider_config.transform_search_vector_store_request(
- vector_store_id=vector_store_id,
- query=query,
- vector_store_search_optional_params=vector_store_search_optional_params,
- api_base=api_base,
- litellm_logging_obj=logging_obj,
- litellm_params=dict(litellm_params),
- )
+ # Check if provider has async transform method
+ if hasattr(vector_store_provider_config, "atransform_search_vector_store_request"):
+ (
+ url,
+ request_body,
+ ) = await vector_store_provider_config.atransform_search_vector_store_request(
+ vector_store_id=vector_store_id,
+ query=query,
+ vector_store_search_optional_params=vector_store_search_optional_params,
+ api_base=api_base,
+ litellm_logging_obj=logging_obj,
+ litellm_params=dict(litellm_params),
+ )
+ else:
+ (
+ url,
+ request_body,
+ ) = vector_store_provider_config.transform_search_vector_store_request(
+ vector_store_id=vector_store_id,
+ query=query,
+ vector_store_search_optional_params=vector_store_search_optional_params,
+ api_base=api_base,
+ litellm_logging_obj=logging_obj,
+ litellm_params=dict(litellm_params),
+ )
all_optional_params: Dict[str, Any] = dict(litellm_params)
all_optional_params.update(vector_store_search_optional_params or {})
headers, signed_json_body = vector_store_provider_config.sign_request(
diff --git a/litellm/llms/databricks/chat/transformation.py b/litellm/llms/databricks/chat/transformation.py
index 2b7f5dd5995..e9ae94307d4 100644
--- a/litellm/llms/databricks/chat/transformation.py
+++ b/litellm/llms/databricks/chat/transformation.py
@@ -298,7 +298,8 @@ class DatabricksConfig(DatabricksBase, OpenAILikeChatConfig, AnthropicConfig):
if "reasoning_effort" in non_default_params and "claude" in model:
optional_params["thinking"] = AnthropicConfig._map_reasoning_effort(
- non_default_params.get("reasoning_effort")
+ reasoning_effort=non_default_params.get("reasoning_effort"),
+ model=model
)
optional_params.pop("reasoning_effort", None)
## handle thinking tokens
diff --git a/litellm/llms/deprecated_providers/palm.py b/litellm/llms/deprecated_providers/palm.py
index 3039222c0e2..657a6fdb229 100644
--- a/litellm/llms/deprecated_providers/palm.py
+++ b/litellm/llms/deprecated_providers/palm.py
@@ -139,7 +139,7 @@ def completion(
)
## COMPLETION CALL
try:
- response = palm.generate_text(prompt=prompt, **inference_params)
+ response = palm.generate_text(prompt=prompt, **inference_params) # type: ignore[attr-defined]
except Exception as e:
raise PalmError(
message=str(e),
diff --git a/litellm/llms/fireworks_ai/chat/transformation.py b/litellm/llms/fireworks_ai/chat/transformation.py
index 86bcd94450f..7ec32fecc46 100644
--- a/litellm/llms/fireworks_ai/chat/transformation.py
+++ b/litellm/llms/fireworks_ai/chat/transformation.py
@@ -236,6 +236,10 @@ class FireworksAIConfig(OpenAIGPTConfig):
disable_add_transform_inline_image_block=disable_add_transform_inline_image_block,
)
filter_value_from_dict(cast(dict, message), "cache_control")
+ # Remove fields not permitted by FireworksAI that may cause:
+ # "Not permitted, field: 'messages[n].provider_specific_fields'"
+ if isinstance(message, dict) and "provider_specific_fields" in message:
+ cast(dict, message).pop("provider_specific_fields", None)
return messages
diff --git a/litellm/llms/gemini/chat/transformation.py b/litellm/llms/gemini/chat/transformation.py
index f6d075392b2..d5a5ab667a6 100644
--- a/litellm/llms/gemini/chat/transformation.py
+++ b/litellm/llms/gemini/chat/transformation.py
@@ -92,7 +92,7 @@ class GoogleAIStudioGeminiConfig(VertexGeminiConfig):
"parallel_tool_calls",
"web_search_options",
]
- if supports_reasoning(model):
+ if supports_reasoning(model, custom_llm_provider="gemini"):
supported_params.append("reasoning_effort")
supported_params.append("thinking")
if self.is_model_gemini_audio_model(model):
diff --git a/litellm/llms/gemini/files/transformation.py b/litellm/llms/gemini/files/transformation.py
index d9ebf69a97a..cc799cfd6aa 100644
--- a/litellm/llms/gemini/files/transformation.py
+++ b/litellm/llms/gemini/files/transformation.py
@@ -4,7 +4,7 @@ Supports writing files to Google AI Studio Files API.
For vertex ai, check out the vertex_ai/files/handler.py file.
"""
import time
-from typing import List, Optional
+from typing import Any, List, Literal, Optional
import httpx
from openai.types.file_deleted import FileDeleted
@@ -17,6 +17,7 @@ from litellm.llms.base_llm.files.transformation import (
)
from litellm.types.llms.gemini import GeminiCreateFilesResponseObject
from litellm.types.llms.openai import (
+ AllMessageValues,
CreateFileRequest,
HttpxBinaryResponseContent,
OpenAICreateFileRequestOptionalParams,
@@ -35,6 +36,27 @@ class GoogleAIStudioFilesHandler(GeminiModelInfo, BaseFilesConfig):
def custom_llm_provider(self) -> LlmProviders:
return LlmProviders.GEMINI
+ def validate_environment(
+ self,
+ headers: dict[Any, Any],
+ model: str,
+ messages: List[AllMessageValues],
+ optional_params: dict[Any, Any],
+ litellm_params: dict[Any, Any],
+ api_key: Optional[str] = None,
+ api_base: Optional[str] = None,
+ ) -> dict[Any, Any]:
+ """
+ Validate environment and add Gemini API key to headers.
+ Google AI Studio uses x-goog-api-key header for authentication.
+ """
+ resolved_api_key = self.get_api_key(api_key)
+ if not resolved_api_key:
+ raise ValueError("GEMINI_API_KEY is required for Google AI Studio file operations")
+
+ headers["x-goog-api-key"] = resolved_api_key
+ return headers
+
def get_complete_url(
self,
api_base: Optional[str],
@@ -56,10 +78,12 @@ class GoogleAIStudioFilesHandler(GeminiModelInfo, BaseFilesConfig):
if not api_base:
raise ValueError("api_base is required")
- if not api_key:
+ # Get API key from multiple sources
+ final_api_key = api_key or litellm_params.get("api_key") or self.get_api_key()
+ if not final_api_key:
raise ValueError("api_key is required")
- url = "{}/{}?key={}".format(api_base, endpoint, api_key)
+ url = "{}/{}?key={}".format(api_base, endpoint, final_api_key)
return url
def get_supported_openai_params(
@@ -180,7 +204,26 @@ class GoogleAIStudioFilesHandler(GeminiModelInfo, BaseFilesConfig):
optional_params: dict,
litellm_params: dict,
) -> tuple[str, dict]:
- raise NotImplementedError("GoogleAIStudioFilesHandler does not support file retrieval")
+ """
+ Get the URL to retrieve a file from Google AI Studio.
+
+ We expect file_id to be the URI (e.g. https://generativelanguage.googleapis.com/v1beta/files/...)
+ as returned by the upload response.
+ """
+ api_key = litellm_params.get("api_key") or self.get_api_key()
+ if not api_key:
+ raise ValueError("api_key is required")
+
+ if file_id.startswith("http"):
+ url = "{}?key={}".format(file_id, api_key)
+ else:
+ # Fallback for just file name (files/...)
+ api_base = self.get_api_base(litellm_params.get("api_base")) or "https://generativelanguage.googleapis.com"
+ api_base = api_base.rstrip("/")
+ url = "{}/v1beta/{}?key={}".format(api_base, file_id, api_key)
+
+ # Return empty params dict - API key is already in URL, no query params needed
+ return url, {}
def transform_retrieve_file_response(
self,
@@ -188,7 +231,42 @@ class GoogleAIStudioFilesHandler(GeminiModelInfo, BaseFilesConfig):
logging_obj: LiteLLMLoggingObj,
litellm_params: dict,
) -> OpenAIFileObject:
- raise NotImplementedError("GoogleAIStudioFilesHandler does not support file retrieval")
+ """
+ Transform Gemini's file retrieval response into OpenAI-style FileObject
+ """
+ try:
+ response_json = raw_response.json()
+
+ # Map Gemini state to OpenAI status
+ gemini_state = response_json.get("state", "STATE_UNSPECIFIED")
+ # Explicitly type status as the Literal union
+ if gemini_state == "ACTIVE":
+ status: Literal["uploaded", "processed", "error"] = "processed"
+ elif gemini_state == "FAILED":
+ status = "error"
+ else:
+ status = "uploaded"
+
+ return OpenAIFileObject(
+ id=response_json.get("uri", ""),
+ bytes=int(response_json.get("sizeBytes", 0)),
+ created_at=int(
+ time.mktime(
+ time.strptime(
+ response_json["createTime"].replace("Z", "+00:00"),
+ "%Y-%m-%dT%H:%M:%S.%f%z",
+ )
+ )
+ ),
+ filename=response_json.get("displayName", ""),
+ object="file",
+ purpose="user_data",
+ status=status,
+ status_details=str(response_json.get("error", "")) if gemini_state == "FAILED" else None,
+ )
+ except Exception as e:
+ verbose_logger.exception(f"Error parsing file retrieve response: {str(e)}")
+ raise ValueError(f"Error parsing file retrieve response: {str(e)}")
def transform_delete_file_request(
self,
@@ -196,7 +274,41 @@ class GoogleAIStudioFilesHandler(GeminiModelInfo, BaseFilesConfig):
optional_params: dict,
litellm_params: dict,
) -> tuple[str, dict]:
- raise NotImplementedError("GoogleAIStudioFilesHandler does not support file deletion")
+ """
+ Transform delete file request for Google AI Studio.
+
+ Args:
+ file_id: The file URI (e.g., "files/abc123" or full URI)
+ optional_params: Optional parameters
+ litellm_params: LiteLLM parameters containing api_key
+
+ Returns:
+ tuple[str, dict]: (url, params) for the DELETE request
+ """
+ api_base = self.get_api_base(litellm_params.get("api_base"))
+ if not api_base:
+ raise ValueError("api_base is required")
+
+ # Get API key from multiple sources (same pattern as get_complete_url)
+ api_key = litellm_params.get("api_key") or self.get_api_key()
+ if not api_key:
+ raise ValueError("api_key is required")
+
+ # Extract file name from URI if full URI is provided
+ # file_id could be "files/abc123" or "https://generativelanguage.googleapis.com/v1beta/files/abc123"
+ if file_id.startswith("http"):
+ # Extract the file path from full URI
+ file_name = file_id.split("/v1beta/")[-1]
+ else:
+ file_name = file_id if file_id.startswith("files/") else f"files/{file_id}"
+
+ # Construct the delete URL
+ url = f"{api_base}/v1beta/{file_name}"
+
+ # Add API key as header (Google AI Studio uses x-goog-api-key header)
+ params: dict = {}
+
+ return url, params
def transform_delete_file_response(
self,
@@ -204,7 +316,34 @@ class GoogleAIStudioFilesHandler(GeminiModelInfo, BaseFilesConfig):
logging_obj: LiteLLMLoggingObj,
litellm_params: dict,
) -> FileDeleted:
- raise NotImplementedError("GoogleAIStudioFilesHandler does not support file deletion")
+ """
+ Transform Gemini's file delete response into OpenAI-style FileDeleted.
+
+ Google AI Studio returns an empty JSON object {} on successful deletion.
+ """
+ try:
+ # Google AI Studio returns {} on successful deletion
+ if raw_response.status_code == 200:
+ # Extract file ID from the request URL if possible
+ file_id = "deleted"
+ if hasattr(raw_response, "request") and raw_response.request:
+ url = str(raw_response.request.url)
+ if "/files/" in url:
+ file_id = url.split("/files/")[-1].split("?")[0]
+ # Add the files/ prefix if not present
+ if not file_id.startswith("files/"):
+ file_id = f"files/{file_id}"
+
+ return FileDeleted(
+ id=file_id,
+ deleted=True,
+ object="file"
+ )
+ else:
+ raise ValueError(f"Failed to delete file: {raw_response.text}")
+ except Exception as e:
+ verbose_logger.exception(f"Error parsing file delete response: {str(e)}")
+ raise ValueError(f"Error parsing file delete response: {str(e)}")
def transform_list_files_request(
self,
diff --git a/litellm/llms/gemini/image_edit/transformation.py b/litellm/llms/gemini/image_edit/transformation.py
index 16541138217..c3ea63ad43b 100644
--- a/litellm/llms/gemini/image_edit/transformation.py
+++ b/litellm/llms/gemini/image_edit/transformation.py
@@ -106,7 +106,10 @@ class GeminiImageEditConfig(BaseImageEditConfig):
generation_config: Dict[str, Any] = {}
if "aspectRatio" in image_edit_optional_request_params:
- generation_config["aspectRatio"] = image_edit_optional_request_params[
+ # Move aspectRatio into imageConfig inside generationConfig
+ if "imageConfig" not in generation_config:
+ generation_config["imageConfig"] = {}
+ generation_config["imageConfig"]["aspectRatio"] = image_edit_optional_request_params[
"aspectRatio"
]
diff --git a/litellm/llms/gemini/image_generation/transformation.py b/litellm/llms/gemini/image_generation/transformation.py
index 63b835df9d0..73aef15e4c7 100644
--- a/litellm/llms/gemini/image_generation/transformation.py
+++ b/litellm/llms/gemini/image_generation/transformation.py
@@ -255,9 +255,11 @@ class GoogleImageGenConfig(BaseImageGenerationConfig):
if "inlineData" in part:
inline_data = part["inlineData"]
if "data" in inline_data:
+ thought_sig = part.get("thoughtSignature")
model_response.data.append(ImageObject(
b64_json=inline_data["data"],
url=None,
+ provider_specific_fields={"thought_signature": thought_sig} if thought_sig else None,
))
# Extract usage metadata for Gemini models
diff --git a/litellm/llms/gigachat/chat/transformation.py b/litellm/llms/gigachat/chat/transformation.py
index 4ce333a1309..f546f356e11 100644
--- a/litellm/llms/gigachat/chat/transformation.py
+++ b/litellm/llms/gigachat/chat/transformation.py
@@ -31,6 +31,16 @@ else:
GIGACHAT_BASE_URL = "https://gigachat.devices.sberbank.ru/api/v1"
+def is_valid_json(value: str) -> bool:
+ """Checks whether the value passed is a valid serialized JSON string"""
+ try:
+ json.loads(value)
+ except json.JSONDecodeError:
+ return False
+ else:
+ return True
+
+
class GigaChatError(BaseLLMException):
"""GigaChat API error."""
@@ -101,7 +111,11 @@ class GigaChatConfig(BaseConfig):
Set up headers with OAuth token.
"""
# Get access token
- credentials = api_key or get_secret_str("GIGACHAT_CREDENTIALS") or get_secret_str("GIGACHAT_API_KEY")
+ credentials = (
+ api_key
+ or get_secret_str("GIGACHAT_CREDENTIALS")
+ or get_secret_str("GIGACHAT_API_KEY")
+ )
access_token = get_access_token(credentials=credentials)
# Store credentials for image uploads
@@ -158,13 +172,10 @@ class GigaChatConfig(BaseConfig):
# Convert tools to functions format
optional_params["functions"] = self._convert_tools_to_functions(value)
elif param == "tool_choice":
- if isinstance(value, dict) and value.get("function"):
- optional_params["function_call"] = {"name": value["function"]["name"]}
- elif value == "auto":
- pass # Default behavior
- elif value == "required":
- # GigaChat doesn't have 'required', handled differently
- pass
+ # Map OpenAI tool_choice to GigaChat function_call
+ mapped_choice = self._map_tool_choice(value)
+ if mapped_choice is not None:
+ optional_params["function_call"] = mapped_choice
elif param == "functions":
optional_params["functions"] = value
elif param == "function_call":
@@ -196,13 +207,57 @@ class GigaChatConfig(BaseConfig):
for tool in tools:
if tool.get("type") == "function":
func = tool.get("function", {})
- functions.append({
- "name": func.get("name", ""),
- "description": func.get("description", ""),
- "parameters": func.get("parameters", {}),
- })
+ functions.append(
+ {
+ "name": func.get("name", ""),
+ "description": func.get("description", ""),
+ "parameters": func.get("parameters", {}),
+ }
+ )
return functions
+ def _map_tool_choice(
+ self, tool_choice: Union[str, dict]
+ ) -> Optional[Union[str, dict]]:
+ """
+ Map OpenAI tool_choice to GigaChat function_call format.
+
+ OpenAI format:
+ - "auto": Call zero, one, or multiple functions (default)
+ - "required": Call one or more functions
+ - "none": Don't call any functions
+ - {"type": "function", "function": {"name": "get_weather"}}: Force specific function
+
+ GigaChat format:
+ - "none": Disable function calls
+ - "auto": Automatic mode (default)
+ - {"name": "get_weather"}: Force specific function
+
+ Args:
+ tool_choice: OpenAI tool_choice value
+
+ Returns:
+ GigaChat function_call value or None
+ """
+ if tool_choice == "none":
+ return "none"
+ elif tool_choice == "auto":
+ return "auto"
+ elif tool_choice == "required":
+ # GigaChat doesn't have a direct "required" equivalent
+ # Use "auto" as the closest behavior
+ return "auto"
+ elif isinstance(tool_choice, dict):
+ # OpenAI format: {"type": "function", "function": {"name": "func_name"}}
+ # GigaChat format: {"name": "func_name"}
+ if tool_choice.get("type") == "function":
+ func_name = tool_choice.get("function", {}).get("name")
+ if func_name:
+ return {"name": func_name}
+
+ # Default to None (don't set function_call)
+ return None
+
def _upload_image(self, image_url: str) -> Optional[str]:
"""
Upload image to GigaChat and return file_id.
@@ -242,8 +297,14 @@ class GigaChatConfig(BaseConfig):
}
# Add optional params
- for key in ["temperature", "top_p", "max_tokens", "stream",
- "repetition_penalty", "profanity_check"]:
+ for key in [
+ "temperature",
+ "top_p",
+ "max_tokens",
+ "stream",
+ "repetition_penalty",
+ "profanity_check",
+ ]:
if key in optional_params:
request_data[key] = optional_params[key]
@@ -275,7 +336,7 @@ class GigaChatConfig(BaseConfig):
elif role == "tool":
message["role"] = "function"
content = message.get("content", "")
- if not isinstance(content, str):
+ if not isinstance(content, str) or not is_valid_json(content):
message["content"] = json.dumps(content, ensure_ascii=False)
# Handle None content
@@ -325,33 +386,7 @@ class GigaChatConfig(BaseConfig):
transformed.append(message)
- # Collapse consecutive user messages
- return self._collapse_user_messages(transformed)
-
- def _collapse_user_messages(self, messages: List[dict]) -> List[dict]:
- """Collapse consecutive user messages into one."""
- collapsed: List[dict] = []
- prev_user_msg: Optional[dict] = None
- content_parts: List[str] = []
-
- for msg in messages:
- if msg.get("role") == "user" and prev_user_msg is not None:
- content_parts.append(msg.get("content", ""))
- else:
- if content_parts and prev_user_msg:
- prev_user_msg["content"] = "\n".join(
- [prev_user_msg.get("content", "")] + content_parts
- )
- content_parts = []
- collapsed.append(msg)
- prev_user_msg = msg if msg.get("role") == "user" else None
-
- if content_parts and prev_user_msg:
- prev_user_msg["content"] = "\n".join(
- [prev_user_msg.get("content", "")] + content_parts
- )
-
- return collapsed
+ return transformed
def transform_response(
self,
@@ -402,14 +437,16 @@ class GigaChatConfig(BaseConfig):
# Convert to tool_calls format
if isinstance(args, dict):
args = json.dumps(args, ensure_ascii=False)
- message_data["tool_calls"] = [{
- "id": f"call_{uuid.uuid4().hex[:24]}",
- "type": "function",
- "function": {
- "name": func_call.get("name", ""),
- "arguments": args,
+ message_data["tool_calls"] = [
+ {
+ "id": f"call_{uuid.uuid4().hex[:24]}",
+ "type": "function",
+ "function": {
+ "name": func_call.get("name", ""),
+ "arguments": args,
+ },
}
- }]
+ ]
message_data.pop("function_call", None)
finish_reason = "tool_calls"
diff --git a/litellm/llms/github_copilot/chat/transformation.py b/litellm/llms/github_copilot/chat/transformation.py
index 50f18cedf9b..be8ad7d0877 100644
--- a/litellm/llms/github_copilot/chat/transformation.py
+++ b/litellm/llms/github_copilot/chat/transformation.py
@@ -1,11 +1,16 @@
-from typing import Any, Optional, Tuple, cast, List
+from typing import List, Optional, Tuple
+
from litellm.exceptions import AuthenticationError
from litellm.llms.openai.openai import OpenAIConfig
from litellm.types.llms.openai import AllMessageValues
from ..authenticator import Authenticator
-from ..common_utils import GetAPIKeyError, GITHUB_COPILOT_API_BASE
+from ..common_utils import (
+ GITHUB_COPILOT_API_BASE,
+ GetAPIKeyError,
+ get_copilot_default_headers,
+)
class GithubCopilotConfig(OpenAIConfig):
@@ -25,9 +30,7 @@ class GithubCopilotConfig(OpenAIConfig):
api_key: Optional[str],
custom_llm_provider: str,
) -> Tuple[Optional[str], Optional[str], str]:
- dynamic_api_base = (
- self.authenticator.get_api_base() or GITHUB_COPILOT_API_BASE
- )
+ dynamic_api_base = self.authenticator.get_api_base() or GITHUB_COPILOT_API_BASE
try:
dynamic_api_key = self.authenticator.get_api_key()
except GetAPIKeyError as e:
@@ -45,14 +48,24 @@ class GithubCopilotConfig(OpenAIConfig):
):
import litellm
- disable_copilot_system_to_assistant = (
- litellm.disable_copilot_system_to_assistant
- )
- if not disable_copilot_system_to_assistant:
- for message in messages:
- if "role" in message and message["role"] == "system":
- cast(Any, message)["role"] = "assistant"
- return messages
+ # Check if system-to-assistant conversion is disabled
+ if litellm.disable_copilot_system_to_assistant:
+ # GitHub Copilot API now supports system prompts for all models (Claude, GPT, etc.)
+ # No conversion needed - just return messages as-is
+ return messages
+
+ # Default behavior: convert system messages to assistant for compatibility
+ transformed_messages = []
+ for message in messages:
+ if message.get("role") == "system":
+ # Convert system message to assistant message
+ transformed_message = message.copy()
+ transformed_message["role"] = "assistant"
+ transformed_messages.append(transformed_message)
+ else:
+ transformed_messages.append(message)
+
+ return transformed_messages
def validate_environment(
self,
@@ -69,6 +82,14 @@ class GithubCopilotConfig(OpenAIConfig):
headers, model, messages, optional_params, litellm_params, api_key, api_base
)
+ # Add Copilot-specific headers (editor-version, user-agent, etc.)
+ try:
+ copilot_api_key = self.authenticator.get_api_key()
+ copilot_headers = get_copilot_default_headers(copilot_api_key)
+ validated_headers = {**copilot_headers, **validated_headers}
+ except GetAPIKeyError:
+ pass # Will be handled later in the request flow
+
# Add X-Initiator header based on message roles
initiator = self._determine_initiator(messages)
validated_headers["X-Initiator"] = initiator
@@ -87,7 +108,7 @@ class GithubCopilotConfig(OpenAIConfig):
For other models, returns standard OpenAI parameters (which may include reasoning_effort for o-series models).
"""
from litellm.utils import supports_reasoning
-
+
# Get base OpenAI parameters
base_params = super().get_supported_openai_params(model)
@@ -118,7 +139,7 @@ class GithubCopilotConfig(OpenAIConfig):
"""
Check if any message contains vision content (images).
Returns True if any message has content with vision-related types, otherwise False.
-
+
Checks for:
- image_url content type (OpenAI format)
- Content items with type 'image_url'
diff --git a/litellm/llms/groq/chat/transformation.py b/litellm/llms/groq/chat/transformation.py
index a75ecd8cc7b..34ea7b03dd9 100644
--- a/litellm/llms/groq/chat/transformation.py
+++ b/litellm/llms/groq/chat/transformation.py
@@ -323,4 +323,12 @@ class GroqChatCompletionStreamingHandler(OpenAIChatCompletionStreamingHandler):
status_code=error.get("code"), message=error.get("message"), body=error
)
+ # Map Groq's 'reasoning' field to LiteLLM's 'reasoning_content' field
+ # Groq returns delta.reasoning, but LiteLLM expects delta.reasoning_content
+ choices = chunk.get("choices", [])
+ for choice in choices:
+ delta = choice.get("delta", {})
+ if "reasoning" in delta:
+ delta["reasoning_content"] = delta.pop("reasoning")
+
return super().chunk_parser(chunk)
diff --git a/litellm/llms/hosted_vllm/chat/transformation.py b/litellm/llms/hosted_vllm/chat/transformation.py
index 1d21490ea31..e955800b947 100644
--- a/litellm/llms/hosted_vllm/chat/transformation.py
+++ b/litellm/llms/hosted_vllm/chat/transformation.py
@@ -23,7 +23,7 @@ from ...openai.chat.gpt_transformation import OpenAIGPTConfig
class HostedVLLMChatConfig(OpenAIGPTConfig):
def get_supported_openai_params(self, model: str) -> List[str]:
params = super().get_supported_openai_params(model)
- params.append("reasoning_effort")
+ params.extend(["reasoning_effort", "thinking"])
return params
def map_openai_params(
@@ -41,6 +41,27 @@ class HostedVLLMChatConfig(OpenAIGPTConfig):
_tools = _remove_strict_from_schema(_tools)
if _tools is not None:
non_default_params["tools"] = _tools
+
+ # Handle thinking parameter - convert Anthropic-style to OpenAI-style reasoning_effort
+ # vLLM is OpenAI-compatible, so it understands reasoning_effort, not thinking
+ # Reference: https://github.com/BerriAI/litellm/issues/19761
+ thinking = non_default_params.pop("thinking", None)
+ if thinking is not None and isinstance(thinking, dict):
+ if thinking.get("type") == "enabled":
+ # Only convert if reasoning_effort not already set
+ if "reasoning_effort" not in non_default_params:
+ budget_tokens = thinking.get("budget_tokens", 0)
+ # Map budget_tokens to reasoning_effort level
+ # Same logic as Anthropic adapter (translate_anthropic_thinking_to_reasoning_effort)
+ if budget_tokens >= 10000:
+ non_default_params["reasoning_effort"] = "high"
+ elif budget_tokens >= 5000:
+ non_default_params["reasoning_effort"] = "medium"
+ elif budget_tokens >= 2000:
+ non_default_params["reasoning_effort"] = "low"
+ else:
+ non_default_params["reasoning_effort"] = "minimal"
+
return super().map_openai_params(
non_default_params, optional_params, model, drop_params
)
diff --git a/litellm/llms/hosted_vllm/embedding/transformation.py b/litellm/llms/hosted_vllm/embedding/transformation.py
new file mode 100644
index 00000000000..9c3e8c6c7cc
--- /dev/null
+++ b/litellm/llms/hosted_vllm/embedding/transformation.py
@@ -0,0 +1,180 @@
+"""
+Hosted VLLM Embedding API Configuration.
+
+This module provides the configuration for hosted VLLM's Embedding API.
+VLLM is OpenAI-compatible and supports embeddings via the /v1/embeddings endpoint.
+
+Docs: https://docs.vllm.ai/en/latest/serving/openai_compatible_server.html
+"""
+
+from typing import TYPE_CHECKING, Any, List, Optional, Union
+
+import httpx
+
+from litellm.llms.base_llm.chat.transformation import BaseLLMException
+from litellm.llms.base_llm.embedding.transformation import BaseEmbeddingConfig
+from litellm.secret_managers.main import get_secret_str
+from litellm.types.llms.openai import AllEmbeddingInputValues, AllMessageValues
+from litellm.types.utils import EmbeddingResponse
+from litellm.utils import convert_to_model_response_object
+
+if TYPE_CHECKING:
+ from litellm.litellm_core_utils.litellm_logging import Logging as _LiteLLMLoggingObj
+
+ LiteLLMLoggingObj = _LiteLLMLoggingObj
+else:
+ LiteLLMLoggingObj = Any
+
+
+class HostedVLLMEmbeddingError(BaseLLMException):
+ """Exception class for Hosted VLLM Embedding errors."""
+
+ pass
+
+
+class HostedVLLMEmbeddingConfig(BaseEmbeddingConfig):
+ """
+ Configuration for Hosted VLLM's Embedding API.
+
+ Reference: https://docs.vllm.ai/en/latest/serving/openai_compatible_server.html
+ """
+
+ def validate_environment(
+ self,
+ headers: dict,
+ model: str,
+ messages: List[AllMessageValues],
+ optional_params: dict,
+ litellm_params: dict,
+ api_key: Optional[str] = None,
+ api_base: Optional[str] = None,
+ ) -> dict:
+ """
+ Validate environment and set up headers for Hosted VLLM API.
+ """
+ if api_key is None:
+ api_key = get_secret_str("HOSTED_VLLM_API_KEY") or "fake-api-key"
+
+ default_headers = {
+ "Content-Type": "application/json",
+ }
+
+ # Only add Authorization header if api_key is not "fake-api-key"
+ if api_key and api_key != "fake-api-key":
+ default_headers["Authorization"] = f"Bearer {api_key}"
+
+ # Merge with existing headers (user's headers take priority)
+ return {**default_headers, **headers}
+
+ def get_complete_url(
+ self,
+ api_base: Optional[str],
+ api_key: Optional[str],
+ model: str,
+ optional_params: dict,
+ litellm_params: dict,
+ stream: Optional[bool] = None,
+ ) -> str:
+ """
+ Get the complete URL for Hosted VLLM Embedding API endpoint.
+ """
+ if api_base is None:
+ api_base = get_secret_str("HOSTED_VLLM_API_BASE")
+ if api_base is None:
+ raise ValueError("api_base is required for hosted_vllm embeddings")
+
+ # Remove trailing slashes
+ api_base = api_base.rstrip("/")
+
+ # Ensure the URL ends with /embeddings
+ if not api_base.endswith("/embeddings"):
+ api_base = f"{api_base}/embeddings"
+
+ return api_base
+
+ def transform_embedding_request(
+ self,
+ model: str,
+ input: AllEmbeddingInputValues,
+ optional_params: dict,
+ headers: dict,
+ ) -> dict:
+ """
+ Transform embedding request to Hosted VLLM format (OpenAI-compatible).
+ """
+ # Ensure input is a list
+ if isinstance(input, str):
+ input = [input]
+
+ # Strip 'hosted_vllm/' prefix if present
+ if model.startswith("hosted_vllm/"):
+ model = model.replace("hosted_vllm/", "", 1)
+
+ return {
+ "model": model,
+ "input": input,
+ **optional_params,
+ }
+
+ def transform_embedding_response(
+ self,
+ model: str,
+ raw_response: httpx.Response,
+ model_response: EmbeddingResponse,
+ logging_obj: LiteLLMLoggingObj,
+ api_key: Optional[str],
+ request_data: dict,
+ optional_params: dict,
+ litellm_params: dict,
+ ) -> EmbeddingResponse:
+ """
+ Transform embedding response from Hosted VLLM format (OpenAI-compatible).
+ """
+ logging_obj.post_call(original_response=raw_response.text)
+
+ # VLLM returns standard OpenAI-compatible embedding response
+ response_json = raw_response.json()
+
+ return convert_to_model_response_object(
+ response_object=response_json,
+ model_response_object=model_response,
+ response_type="embedding",
+ )
+
+ def get_supported_openai_params(self, model: str) -> list:
+ """
+ Get list of supported OpenAI parameters for Hosted VLLM embeddings.
+ """
+ return [
+ "timeout",
+ "dimensions",
+ "encoding_format",
+ "user",
+ ]
+
+ def map_openai_params(
+ self,
+ non_default_params: dict,
+ optional_params: dict,
+ model: str,
+ drop_params: bool,
+ ) -> dict:
+ """
+ Map OpenAI parameters to Hosted VLLM format.
+ """
+ for param, value in non_default_params.items():
+ if param in self.get_supported_openai_params(model):
+ optional_params[param] = value
+ return optional_params
+
+ def get_error_class(
+ self, error_message: str, status_code: int, headers: Union[dict, httpx.Headers]
+ ) -> BaseLLMException:
+ """
+ Get the error class for Hosted VLLM errors.
+ """
+ return HostedVLLMEmbeddingError(
+ message=error_message,
+ status_code=status_code,
+ headers=headers,
+ )
diff --git a/litellm/llms/minimax/chat/transformation.py b/litellm/llms/minimax/chat/transformation.py
index ed80ff8aed1..3e9dc0209f2 100644
--- a/litellm/llms/minimax/chat/transformation.py
+++ b/litellm/llms/minimax/chat/transformation.py
@@ -1,11 +1,12 @@
"""
MiniMax OpenAI transformation config - extends OpenAI chat config for MiniMax's OpenAI-compatible API
"""
-from typing import Optional
+from typing import List, Optional, Tuple
import litellm
from litellm.llms.openai.chat.gpt_transformation import OpenAIGPTConfig
from litellm.secret_managers.main import get_secret_str
+from litellm.types.llms.openai import AllMessageValues, ChatCompletionToolParam
class MinimaxChatConfig(OpenAIGPTConfig):
@@ -73,11 +74,33 @@ class MinimaxChatConfig(OpenAIGPTConfig):
else:
return f"{base_url}/v1/chat/completions"
+ def remove_cache_control_flag_from_messages_and_tools(
+ self,
+ model: str,
+ messages: List[AllMessageValues],
+ tools: Optional[List[ChatCompletionToolParam]] = None,
+ ) -> Tuple[List[AllMessageValues], Optional[List[ChatCompletionToolParam]]]:
+ """
+ Override to preserve cache_control for MiniMax.
+ MiniMax supports cache_control - don't strip it.
+ """
+ # MiniMax supports cache_control, so return messages and tools unchanged
+ return messages, tools
+
def get_supported_openai_params(self, model: str) -> list:
"""
Get supported OpenAI parameters for MiniMax.
- Adds reasoning_split to the list of supported params.
+ Adds reasoning_split and thinking to the list of supported params.
"""
base_params = super().get_supported_openai_params(model=model)
- return base_params + ["reasoning_split"]
+ additional_params = ["reasoning_split"]
+
+ # Add thinking parameter if model supports reasoning
+ try:
+ if litellm.supports_reasoning(model=model, custom_llm_provider="minimax"):
+ additional_params.append("thinking")
+ except Exception:
+ pass
+
+ return base_params + additional_params
diff --git a/litellm/llms/oci/chat/transformation.py b/litellm/llms/oci/chat/transformation.py
index 7af7be2094a..84f39ef2525 100644
--- a/litellm/llms/oci/chat/transformation.py
+++ b/litellm/llms/oci/chat/transformation.py
@@ -32,6 +32,7 @@ from litellm.types.llms.oci import (
OCICompletionResponse,
OCIContentPartUnion,
OCIImageContentPart,
+ OCIImageUrl,
OCIMessage,
OCIRoles,
OCIServingMode,
@@ -1129,7 +1130,7 @@ def adapt_messages_to_generic_oci_standard_content_message(
image_url = image_url.get("url")
if not isinstance(image_url, str):
raise Exception("Prop `image_url` must be a string or an object with a `url` property")
- new_content.append(OCIImageContentPart(imageUrl=image_url))
+ new_content.append(OCIImageContentPart(imageUrl=OCIImageUrl(url=image_url)))
return OCIMessage(
role=open_ai_to_generic_oci_role_map[role],
diff --git a/litellm/llms/openai/chat/gpt_5_transformation.py b/litellm/llms/openai/chat/gpt_5_transformation.py
index 3fffa335fdc..05c003c8b7a 100644
--- a/litellm/llms/openai/chat/gpt_5_transformation.py
+++ b/litellm/llms/openai/chat/gpt_5_transformation.py
@@ -19,7 +19,9 @@ class OpenAIGPT5Config(OpenAIGPTConfig):
@classmethod
def is_model_gpt_5_model(cls, model: str) -> bool:
- return "gpt-5" in model
+ # gpt-5-chat* behaves like a regular chat model (supports temperature, etc.)
+ # Don't route it through GPT-5 reasoning-specific parameter restrictions.
+ return "gpt-5" in model and "gpt-5-chat" not in model
@classmethod
def is_model_gpt_5_codex_model(cls, model: str) -> bool:
diff --git a/litellm/llms/openai/chat/guardrail_translation/handler.py b/litellm/llms/openai/chat/guardrail_translation/handler.py
index d0ed3f165cc..c406f502b45 100644
--- a/litellm/llms/openai/chat/guardrail_translation/handler.py
+++ b/litellm/llms/openai/chat/guardrail_translation/handler.py
@@ -21,7 +21,13 @@ from litellm._logging import verbose_proxy_logger
from litellm.llms.base_llm.guardrail_translation.base_translation import BaseTranslation
from litellm.main import stream_chunk_builder
from litellm.types.llms.openai import ChatCompletionToolParam
-from litellm.types.utils import Choices, GenericGuardrailAPIInputs, ModelResponse, ModelResponseStream, StreamingChoices
+from litellm.types.utils import (
+ Choices,
+ GenericGuardrailAPIInputs,
+ ModelResponse,
+ ModelResponseStream,
+ StreamingChoices,
+)
if TYPE_CHECKING:
from litellm.integrations.custom_guardrail import CustomGuardrail
@@ -80,13 +86,17 @@ class OpenAIChatCompletionsHandler(BaseTranslation):
if tool_calls_to_check:
inputs["tool_calls"] = tool_calls_to_check # type: ignore
if messages:
- inputs["structured_messages"] = (
- messages # pass the openai /chat/completions messages to the guardrail, as-is
- )
+ inputs[
+ "structured_messages"
+ ] = messages # pass the openai /chat/completions messages to the guardrail, as-is
# Pass tools (function definitions) to the guardrail
tools = data.get("tools")
if tools:
inputs["tools"] = tools
+ # Include model information if available
+ model = data.get("model")
+ if model:
+ inputs["model"] = model
guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
inputs=inputs,
@@ -297,6 +307,9 @@ class OpenAIChatCompletionsHandler(BaseTranslation):
inputs["images"] = images_to_check
if tool_calls_to_check:
inputs["tool_calls"] = tool_calls_to_check # type: ignore
+ # Include model information from the response if available
+ if hasattr(response, "model") and response.model:
+ inputs["model"] = response.model
guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
inputs=inputs,
@@ -355,14 +368,17 @@ class OpenAIChatCompletionsHandler(BaseTranslation):
# check if the stream has ended
has_stream_ended = False
for chunk in responses_so_far:
- if chunk.choices[0].finish_reason is not None:
+ if chunk.choices and chunk.choices[0].finish_reason is not None:
has_stream_ended = True
break
if has_stream_ended:
# convert to model response
model_response = cast(
- ModelResponse, stream_chunk_builder(chunks=responses_so_far, logging_obj=litellm_logging_obj)
+ ModelResponse,
+ stream_chunk_builder(
+ chunks=responses_so_far, logging_obj=litellm_logging_obj
+ ),
)
# run process_output_response
await self.process_output_response(
@@ -417,6 +433,13 @@ class OpenAIChatCompletionsHandler(BaseTranslation):
inputs = GenericGuardrailAPIInputs(texts=texts_to_check)
if images_to_check:
inputs["images"] = images_to_check
+ # Include model information from the first response if available
+ if (
+ responses_so_far
+ and hasattr(responses_so_far[0], "model")
+ and responses_so_far[0].model
+ ):
+ inputs["model"] = responses_so_far[0].model
guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
inputs=inputs,
request_data=request_data,
diff --git a/litellm/llms/openai/common_utils.py b/litellm/llms/openai/common_utils.py
index 8bcecd35232..ce470f04aca 100644
--- a/litellm/llms/openai/common_utils.py
+++ b/litellm/llms/openai/common_utils.py
@@ -15,14 +15,12 @@ if TYPE_CHECKING:
from aiohttp import ClientSession
import litellm
-from litellm._logging import verbose_logger
from litellm.llms.base_llm.chat.transformation import BaseLLMException
from litellm.llms.custom_httpx.http_handler import (
_DEFAULT_TTL_FOR_HTTPX_CLIENTS,
AsyncHTTPHandler,
get_ssl_configuration,
)
-from litellm.types.utils import LlmProviders
class OpenAIError(BaseLLMException):
@@ -205,67 +203,30 @@ class BaseOpenAILLM:
if litellm.aclient_session is not None:
return litellm.aclient_session
- # Use the global cached client system to prevent memory leaks (issue #14540)
- # This routes through get_async_httpx_client() which provides TTL-based caching
- from litellm.llms.custom_httpx.http_handler import get_async_httpx_client
+ # Get unified SSL configuration
+ ssl_config = get_ssl_configuration()
- try:
- # Get SSL config and include in params for proper cache key
- ssl_config = get_ssl_configuration()
- params = {"ssl_verify": ssl_config} if ssl_config is not None else {}
- params["disable_aiohttp_transport"] = litellm.disable_aiohttp_transport
-
- # Get a cached AsyncHTTPHandler which manages the httpx.AsyncClient
- cached_handler = get_async_httpx_client(
- llm_provider=LlmProviders.OPENAI, # Cache key includes provider
- params=params, # Include SSL config in cache key
+ return httpx.AsyncClient(
+ verify=ssl_config,
+ transport=AsyncHTTPHandler._create_async_transport(
+ ssl_context=ssl_config
+ if isinstance(ssl_config, ssl.SSLContext)
+ else None,
+ ssl_verify=ssl_config if isinstance(ssl_config, bool) else None,
shared_session=shared_session,
- )
- # Return the underlying httpx client from the handler
- return cached_handler.client
- except (ImportError, AttributeError, KeyError) as e:
- # Fallback to creating a client directly if caching system unavailable
- # This preserves backwards compatibility
- verbose_logger.debug(
- f"Client caching unavailable ({type(e).__name__}), using direct client creation"
- )
- ssl_config = get_ssl_configuration()
- return httpx.AsyncClient(
- verify=ssl_config,
- transport=AsyncHTTPHandler._create_async_transport(
- ssl_context=ssl_config
- if isinstance(ssl_config, ssl.SSLContext)
- else None,
- ssl_verify=ssl_config if isinstance(ssl_config, bool) else None,
- shared_session=shared_session,
- ),
- follow_redirects=True,
- )
+ ),
+ follow_redirects=True,
+ )
@staticmethod
def _get_sync_http_client() -> Optional[httpx.Client]:
if litellm.client_session is not None:
return litellm.client_session
- # Use the global cached client system to prevent memory leaks (issue #14540)
- from litellm.llms.custom_httpx.http_handler import _get_httpx_client
+ # Get unified SSL configuration
+ ssl_config = get_ssl_configuration()
- try:
- # Get SSL config and include in params for proper cache key
- ssl_config = get_ssl_configuration()
- params = {"ssl_verify": ssl_config} if ssl_config is not None else None
-
- # Get a cached HTTPHandler which manages the httpx.Client
- cached_handler = _get_httpx_client(params=params)
- # Return the underlying httpx client from the handler
- return cached_handler.client
- except (ImportError, AttributeError, KeyError) as e:
- # Fallback to creating a client directly if caching system unavailable
- verbose_logger.debug(
- f"Client caching unavailable ({type(e).__name__}), using direct client creation"
- )
- ssl_config = get_ssl_configuration()
- return httpx.Client(
- verify=ssl_config,
- follow_redirects=True,
- )
+ return httpx.Client(
+ verify=ssl_config,
+ follow_redirects=True,
+ )
diff --git a/litellm/llms/openai/completion/guardrail_translation/handler.py b/litellm/llms/openai/completion/guardrail_translation/handler.py
index 73d08cfead4..1f8c6159da0 100644
--- a/litellm/llms/openai/completion/guardrail_translation/handler.py
+++ b/litellm/llms/openai/completion/guardrail_translation/handler.py
@@ -9,6 +9,7 @@ from typing import TYPE_CHECKING, Any, Optional
from litellm._logging import verbose_proxy_logger
from litellm.llms.base_llm.guardrail_translation.base_translation import BaseTranslation
+from litellm.types.utils import GenericGuardrailAPIInputs
if TYPE_CHECKING:
from litellm.integrations.custom_guardrail import CustomGuardrail
@@ -53,8 +54,13 @@ class OpenAITextCompletionHandler(BaseTranslation):
if isinstance(prompt, str):
# Single string prompt
+ inputs = GenericGuardrailAPIInputs(texts=[prompt])
+ # Include model information if available
+ model = data.get("model")
+ if model:
+ inputs["model"] = model
guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
- inputs={"texts": [prompt]},
+ inputs=inputs,
request_data=data,
input_type="request",
logging_obj=litellm_logging_obj,
@@ -80,8 +86,13 @@ class OpenAITextCompletionHandler(BaseTranslation):
text_indices.append(idx)
if texts_to_check:
+ inputs = GenericGuardrailAPIInputs(texts=texts_to_check)
+ # Include model information if available
+ model = data.get("model")
+ if model:
+ inputs["model"] = model
guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
- inputs={"texts": texts_to_check},
+ inputs=inputs,
request_data=data,
input_type="request",
logging_obj=litellm_logging_obj,
@@ -154,8 +165,12 @@ class OpenAITextCompletionHandler(BaseTranslation):
if user_metadata:
request_data["litellm_metadata"] = user_metadata
+ inputs = GenericGuardrailAPIInputs(texts=texts_to_check)
+ # Include model information from the response if available
+ if hasattr(response, "model") and response.model:
+ inputs["model"] = response.model
guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
- inputs={"texts": texts_to_check},
+ inputs=inputs,
request_data=request_data,
input_type="response",
logging_obj=litellm_logging_obj,
diff --git a/litellm/llms/openai/embeddings/guardrail_translation/__init__.py b/litellm/llms/openai/embeddings/guardrail_translation/__init__.py
new file mode 100644
index 00000000000..a60662282ca
--- /dev/null
+++ b/litellm/llms/openai/embeddings/guardrail_translation/__init__.py
@@ -0,0 +1,13 @@
+"""OpenAI Embeddings handler for Unified Guardrails."""
+
+from litellm.llms.openai.embeddings.guardrail_translation.handler import (
+ OpenAIEmbeddingsHandler,
+)
+from litellm.types.utils import CallTypes
+
+guardrail_translation_mappings = {
+ CallTypes.embedding: OpenAIEmbeddingsHandler,
+ CallTypes.aembedding: OpenAIEmbeddingsHandler,
+}
+
+__all__ = ["guardrail_translation_mappings", "OpenAIEmbeddingsHandler"]
diff --git a/litellm/llms/openai/embeddings/guardrail_translation/handler.py b/litellm/llms/openai/embeddings/guardrail_translation/handler.py
new file mode 100644
index 00000000000..7458020e109
--- /dev/null
+++ b/litellm/llms/openai/embeddings/guardrail_translation/handler.py
@@ -0,0 +1,179 @@
+"""
+OpenAI Embeddings Handler for Unified Guardrails
+
+This module provides guardrail translation support for OpenAI's embeddings endpoint.
+The handler processes the 'input' parameter for guardrails.
+"""
+
+from typing import TYPE_CHECKING, Any, List, Optional, Union
+
+from litellm._logging import verbose_proxy_logger
+from litellm.llms.base_llm.guardrail_translation.base_translation import BaseTranslation
+from litellm.types.utils import GenericGuardrailAPIInputs
+
+if TYPE_CHECKING:
+ from litellm.integrations.custom_guardrail import CustomGuardrail
+ from litellm.types.utils import EmbeddingResponse
+
+
+class OpenAIEmbeddingsHandler(BaseTranslation):
+ """
+ Handler for processing OpenAI embeddings requests with guardrails.
+
+ This class provides methods to:
+ 1. Process input text (pre-call hook)
+ 2. Process output response (post-call hook) - embeddings don't typically need output guardrails
+
+ The handler specifically processes the 'input' parameter which can be:
+ - A single string
+ - A list of strings (for batch embeddings)
+ - A list of integers (token IDs - not processed by guardrails)
+ - A list of lists of integers (batch token IDs - not processed by guardrails)
+ """
+
+ async def process_input_messages(
+ self,
+ data: dict,
+ guardrail_to_apply: "CustomGuardrail",
+ litellm_logging_obj: Optional[Any] = None,
+ ) -> Any:
+ """
+ Process input text by applying guardrails to text content.
+
+ Args:
+ data: Request data dictionary containing 'input' parameter
+ guardrail_to_apply: The guardrail instance to apply
+ litellm_logging_obj: Optional logging object
+
+ Returns:
+ Modified data with guardrails applied to input
+ """
+ input_data = data.get("input")
+ if input_data is None:
+ verbose_proxy_logger.debug(
+ "OpenAI Embeddings: No input found in request data"
+ )
+ return data
+
+ if isinstance(input_data, str):
+ data = await self._process_string_input(
+ data, input_data, guardrail_to_apply, litellm_logging_obj
+ )
+ elif isinstance(input_data, list):
+ data = await self._process_list_input(
+ data, input_data, guardrail_to_apply, litellm_logging_obj
+ )
+ else:
+ verbose_proxy_logger.warning(
+ "OpenAI Embeddings: Unexpected input type: %s. Expected string or list.",
+ type(input_data),
+ )
+
+ return data
+
+ async def _process_string_input(
+ self,
+ data: dict,
+ input_data: str,
+ guardrail_to_apply: "CustomGuardrail",
+ litellm_logging_obj: Optional[Any],
+ ) -> dict:
+ """Process a single string input through the guardrail."""
+ inputs = GenericGuardrailAPIInputs(texts=[input_data])
+ if model := data.get("model"):
+ inputs["model"] = model
+
+ guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
+ inputs=inputs,
+ request_data=data,
+ input_type="request",
+ logging_obj=litellm_logging_obj,
+ )
+
+ if guardrailed_texts := guardrailed_inputs.get("texts"):
+ data["input"] = guardrailed_texts[0]
+ verbose_proxy_logger.debug(
+ "OpenAI Embeddings: Applied guardrail to string input. "
+ "Original length: %d, New length: %d",
+ len(input_data),
+ len(data["input"]),
+ )
+
+ return data
+
+ async def _process_list_input(
+ self,
+ data: dict,
+ input_data: List[Union[str, int, List[int]]],
+ guardrail_to_apply: "CustomGuardrail",
+ litellm_logging_obj: Optional[Any],
+ ) -> dict:
+ """Process a list input through the guardrail (if it contains strings)."""
+ if len(input_data) == 0:
+ return data
+
+ first_item = input_data[0]
+
+ # Skip non-text inputs (token IDs)
+ if isinstance(first_item, (int, list)):
+ verbose_proxy_logger.debug(
+ "OpenAI Embeddings: Input is token IDs, skipping guardrail processing"
+ )
+ return data
+
+ if not isinstance(first_item, str):
+ verbose_proxy_logger.warning(
+ "OpenAI Embeddings: Unexpected input list item type: %s",
+ type(first_item),
+ )
+ return data
+
+ # List of strings - apply guardrail
+ inputs = GenericGuardrailAPIInputs(texts=input_data) # type: ignore
+ if model := data.get("model"):
+ inputs["model"] = model
+
+ guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
+ inputs=inputs,
+ request_data=data,
+ input_type="request",
+ logging_obj=litellm_logging_obj,
+ )
+
+ if guardrailed_texts := guardrailed_inputs.get("texts"):
+ data["input"] = guardrailed_texts
+ verbose_proxy_logger.debug(
+ "OpenAI Embeddings: Applied guardrail to %d inputs",
+ len(guardrailed_texts),
+ )
+
+ return data
+
+ async def process_output_response(
+ self,
+ response: "EmbeddingResponse",
+ guardrail_to_apply: "CustomGuardrail",
+ litellm_logging_obj: Optional[Any] = None,
+ user_api_key_dict: Optional[Any] = None,
+ ) -> Any:
+ """
+ Process output response - embeddings responses contain vectors, not text.
+
+ For embeddings, the output is numerical vectors, so there's typically
+ no text content to apply guardrails to. This method is a no-op but
+ is included for interface consistency.
+
+ Args:
+ response: Embedding response object
+ guardrail_to_apply: The guardrail instance to apply
+ litellm_logging_obj: Optional logging object
+ user_api_key_dict: User API key metadata
+
+ Returns:
+ Unmodified response (embeddings don't have text output to guard)
+ """
+ verbose_proxy_logger.debug(
+ "OpenAI Embeddings: Output response processing skipped - "
+ "embeddings contain vectors, not text"
+ )
+ return response
diff --git a/litellm/llms/openai/image_generation/cost_calculator.py b/litellm/llms/openai/image_generation/cost_calculator.py
index 35caaf6e9b1..988d5626134 100644
--- a/litellm/llms/openai/image_generation/cost_calculator.py
+++ b/litellm/llms/openai/image_generation/cost_calculator.py
@@ -8,8 +8,7 @@ from typing import Optional
from litellm import verbose_logger
from litellm.litellm_core_utils.llm_cost_calc.utils import generic_cost_per_token
-from litellm.responses.utils import ResponseAPILoggingUtils
-from litellm.types.utils import ImageResponse
+from litellm.types.utils import ImageResponse, Usage
def cost_calculator(
@@ -39,11 +38,18 @@ def cost_calculator(
)
return 0.0
- # Transform ImageUsage to Usage using the existing helper
- # ImageUsage has the same format as ResponseAPIUsage
- chat_usage = ResponseAPILoggingUtils._transform_response_api_usage_to_chat_usage(
- usage
- )
+ # If usage is already a Usage object with completion_tokens_details set,
+ # use it directly (it was already transformed in convert_to_image_response)
+ if isinstance(usage, Usage) and usage.completion_tokens_details is not None:
+ chat_usage = usage
+ else:
+ # Transform ImageUsage to Usage using the existing helper
+ # ImageUsage has the same format as ResponseAPIUsage
+ from litellm.responses.utils import ResponseAPILoggingUtils
+
+ chat_usage = ResponseAPILoggingUtils._transform_response_api_usage_to_chat_usage(
+ usage
+ )
# Use generic_cost_per_token for cost calculation
prompt_cost, completion_cost = generic_cost_per_token(
diff --git a/litellm/llms/openai/image_generation/guardrail_translation/handler.py b/litellm/llms/openai/image_generation/guardrail_translation/handler.py
index 842a64b1878..e6340ba4705 100644
--- a/litellm/llms/openai/image_generation/guardrail_translation/handler.py
+++ b/litellm/llms/openai/image_generation/guardrail_translation/handler.py
@@ -9,6 +9,7 @@ from typing import TYPE_CHECKING, Any, Optional
from litellm._logging import verbose_proxy_logger
from litellm.llms.base_llm.guardrail_translation.base_translation import BaseTranslation
+from litellm.types.utils import GenericGuardrailAPIInputs
if TYPE_CHECKING:
from litellm.integrations.custom_guardrail import CustomGuardrail
@@ -52,8 +53,13 @@ class OpenAIImageGenerationHandler(BaseTranslation):
# Apply guardrail to the prompt
if isinstance(prompt, str):
+ inputs = GenericGuardrailAPIInputs(texts=[prompt])
+ # Include model information if available
+ model = data.get("model")
+ if model:
+ inputs["model"] = model
guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
- inputs={"texts": [prompt]},
+ inputs=inputs,
request_data=data,
input_type="request",
logging_obj=litellm_logging_obj,
diff --git a/litellm/llms/openai/openai.py b/litellm/llms/openai/openai.py
index 4d623097478..8a8070240da 100644
--- a/litellm/llms/openai/openai.py
+++ b/litellm/llms/openai/openai.py
@@ -1923,10 +1923,10 @@ class OpenAIBatchesAPI(BaseLLM):
self,
cancel_batch_data: CancelBatchRequest,
openai_client: AsyncOpenAI,
- ) -> Batch:
+ ) -> LiteLLMBatch:
verbose_logger.debug("async cancelling batch, args= %s", cancel_batch_data)
response = await openai_client.batches.cancel(**cancel_batch_data)
- return response
+ return LiteLLMBatch(**response.model_dump())
def cancel_batch(
self,
@@ -1962,8 +1962,13 @@ class OpenAIBatchesAPI(BaseLLM):
cancel_batch_data=cancel_batch_data, openai_client=openai_client
)
+ # At this point, openai_client is guaranteed to be a sync OpenAI client
+ if not isinstance(openai_client, OpenAI):
+ raise ValueError(
+ "OpenAI client is not an instance of OpenAI. Make sure you passed a sync OpenAI client."
+ )
response = openai_client.batches.cancel(**cancel_batch_data)
- return response
+ return LiteLLMBatch(**response.model_dump())
async def alist_batches(
self,
diff --git a/litellm/llms/openai/realtime/handler.py b/litellm/llms/openai/realtime/handler.py
index fd04ac4d458..ef9cc43c3e1 100644
--- a/litellm/llms/openai/realtime/handler.py
+++ b/litellm/llms/openai/realtime/handler.py
@@ -16,6 +16,62 @@ from ..openai import OpenAIChatCompletion
class OpenAIRealtime(OpenAIChatCompletion):
+ """
+ Base handler for OpenAI-compatible realtime WebSocket connections.
+
+ Subclasses can override template methods to customize:
+ - _get_default_api_base(): Default API base URL
+ - _get_additional_headers(): Extra headers beyond Authorization
+ - _get_ssl_config(): SSL configuration for WebSocket connection
+ """
+
+ def _get_default_api_base(self) -> str:
+ """
+ Get the default API base URL for this provider.
+ Override this in subclasses to set provider-specific defaults.
+ """
+ return "https://api.openai.com/"
+
+ def _get_additional_headers(self, api_key: str) -> dict:
+ """
+ Get additional headers beyond Authorization.
+ Override this in subclasses to customize headers (e.g., remove OpenAI-Beta).
+
+ Args:
+ api_key: API key for authentication
+
+ Returns:
+ Dictionary of additional headers
+ """
+ return {
+ "Authorization": f"Bearer {api_key}",
+ "OpenAI-Beta": "realtime=v1",
+ }
+
+ def _get_ssl_config(self, url: str) -> Any:
+ """
+ Get SSL configuration for WebSocket connection.
+ Override this in subclasses to customize SSL behavior.
+
+ Args:
+ url: WebSocket URL (ws:// or wss://)
+
+ Returns:
+ SSL configuration (None, True, or SSLContext)
+ """
+ if url.startswith("ws://"):
+ return None
+
+ # Use the shared SSL context which respects custom CA certs and SSL settings
+ ssl_config = get_shared_realtime_ssl_context()
+
+ # If ssl_config is False (ssl_verify=False), websockets library needs True instead
+ # to establish connection without verification (False would fail)
+ if ssl_config is False:
+ return True
+
+ return ssl_config
+
def _construct_url(self, api_base: str, query_params: RealtimeQueryParams) -> str:
"""
Construct the backend websocket URL with all query parameters (including 'model').
@@ -45,8 +101,9 @@ class OpenAIRealtime(OpenAIChatCompletion):
):
import websockets
from websockets.asyncio.client import ClientConnection
+
if api_base is None:
- api_base = "https://api.openai.com/"
+ api_base = self._get_default_api_base()
if api_key is None:
raise ValueError("api_key is required for OpenAI realtime calls")
@@ -56,30 +113,27 @@ class OpenAIRealtime(OpenAIChatCompletion):
url = self._construct_url(api_base, query_params)
try:
- # Only use SSL context for secure websocket connections (wss://)
- # websockets library doesn't accept ssl argument for ws:// URIs
- ssl_context = None if url.startswith("ws://") else get_shared_realtime_ssl_context()
+ # Get provider-specific SSL configuration
+ ssl_config = self._get_ssl_config(url)
+
+ # Get provider-specific headers
+ headers = self._get_additional_headers(api_key)
+
# Log a masked request preview consistent with other endpoints.
logging_obj.pre_call(
input=None,
api_key=api_key,
additional_args={
"api_base": url,
- "headers": {
- "Authorization": f"Bearer {api_key}",
- "OpenAI-Beta": "realtime=v1",
- },
+ "headers": headers,
"complete_input_dict": {"query_params": query_params},
},
)
async with websockets.connect( # type: ignore
url,
- additional_headers={
- "Authorization": f"Bearer {api_key}", # type: ignore
- "OpenAI-Beta": "realtime=v1",
- },
+ additional_headers=headers, # type: ignore
max_size=REALTIME_WEBSOCKET_MAX_MESSAGE_SIZE_BYTES,
- ssl=ssl_context,
+ ssl=ssl_config,
) as backend_ws:
realtime_streaming = RealTimeStreaming(
websocket, cast(ClientConnection, backend_ws), logging_obj
diff --git a/litellm/llms/openai/responses/guardrail_translation/handler.py b/litellm/llms/openai/responses/guardrail_translation/handler.py
index 9b8f15c7623..ad3d4c932d4 100644
--- a/litellm/llms/openai/responses/guardrail_translation/handler.py
+++ b/litellm/llms/openai/responses/guardrail_translation/handler.py
@@ -105,6 +105,10 @@ class OpenAIResponsesHandler(BaseTranslation):
inputs["tools"] = tools_to_check
if structured_messages:
inputs["structured_messages"] = structured_messages # type: ignore
+ # Include model information if available
+ model = data.get("model")
+ if model:
+ inputs["model"] = model
guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
inputs=inputs,
@@ -150,6 +154,10 @@ class OpenAIResponsesHandler(BaseTranslation):
inputs["tools"] = tools_to_check
if structured_messages:
inputs["structured_messages"] = structured_messages # type: ignore
+ # Include model information if available
+ model = data.get("model")
+ if model:
+ inputs["model"] = model
guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
inputs=inputs,
request_data=data,
@@ -311,9 +319,7 @@ class OpenAIResponsesHandler(BaseTranslation):
return response
if not response_output:
- verbose_proxy_logger.debug(
- "OpenAI Responses API: Empty output in response"
- )
+ verbose_proxy_logger.debug("OpenAI Responses API: Empty output in response")
return response
# Step 1: Extract all text content and tool calls from response output
@@ -344,6 +350,14 @@ class OpenAIResponsesHandler(BaseTranslation):
inputs["images"] = images_to_check
if tool_calls_to_check:
inputs["tool_calls"] = tool_calls_to_check
+ # Include model information from the response if available
+ response_model = None
+ if isinstance(response, dict):
+ response_model = response.get("model")
+ elif hasattr(response, "model"):
+ response_model = getattr(response, "model", None)
+ if response_model:
+ inputs["model"] = response_model
guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
inputs=inputs,
@@ -388,12 +402,15 @@ class OpenAIResponsesHandler(BaseTranslation):
tool_calls = model_response_stream.choices[0].delta.tool_calls
if tool_calls:
+ inputs = GenericGuardrailAPIInputs()
+ inputs["tool_calls"] = cast(
+ List[ChatCompletionToolCallChunk], tool_calls
+ )
+ # Include model information if available
+ if hasattr(model_response_stream, "model") and model_response_stream.model:
+ inputs["model"] = model_response_stream.model
_guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
- inputs={
- "tool_calls": cast(
- List[ChatCompletionToolCallChunk], tool_calls
- )
- },
+ inputs=inputs,
request_data={},
input_type="response",
logging_obj=litellm_logging_obj,
@@ -408,29 +425,42 @@ class OpenAIResponsesHandler(BaseTranslation):
handle_raw_dict_callback=None,
)
- tool_calls = model_response_choices[0].message.tool_calls
- text = model_response_choices[0].message.content
- guardrail_inputs = GenericGuardrailAPIInputs()
- if text:
- guardrail_inputs["texts"] = [text]
- if tool_calls:
- guardrail_inputs["tool_calls"] = cast(
- List[ChatCompletionToolCallChunk], tool_calls
- )
- if tool_calls:
- _guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
- inputs=guardrail_inputs,
- request_data={},
- input_type="response",
- logging_obj=litellm_logging_obj,
- )
- return responses_so_far
+ if model_response_choices:
+ tool_calls = model_response_choices[0].message.tool_calls
+ text = model_response_choices[0].message.content
+ guardrail_inputs = GenericGuardrailAPIInputs()
+ if text:
+ guardrail_inputs["texts"] = [text]
+ if tool_calls:
+ guardrail_inputs["tool_calls"] = cast(
+ List[ChatCompletionToolCallChunk], tool_calls
+ )
+ # Include model information from the response if available
+ response_model = final_chunk.get("response", {}).get("model")
+ if response_model:
+ guardrail_inputs["model"] = response_model
+ if tool_calls or text:
+ _guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
+ inputs=guardrail_inputs,
+ request_data={},
+ input_type="response",
+ logging_obj=litellm_logging_obj,
+ )
+ return responses_so_far
+ else:
+ verbose_proxy_logger.debug("Skipping output guardrail - model response has no choices")
# model_response_stream = OpenAiResponsesToChatCompletionStreamIterator.translate_responses_chunk_to_openai_stream(final_chunk)
# tool_calls = model_response_stream.choices[0].tool_calls
# convert openai response to model response
string_so_far = self.get_streaming_string_so_far(responses_so_far)
+ inputs = GenericGuardrailAPIInputs(texts=[string_so_far])
+ # Try to get model from the final chunk if available
+ if isinstance(final_chunk, dict):
+ response_model = final_chunk.get("response", {}).get("model") if isinstance(final_chunk.get("response"), dict) else None
+ if response_model:
+ inputs["model"] = response_model
_guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
- inputs={"texts": [string_so_far]},
+ inputs=inputs,
request_data={},
input_type="response",
logging_obj=litellm_logging_obj,
@@ -484,11 +514,9 @@ class OpenAIResponsesHandler(BaseTranslation):
# Check if it's an OutputText with text
if isinstance(content_item, OutputText):
if content_item.text:
-
return True
elif isinstance(content_item, dict):
if content_item.get("text"):
-
return True
return False
diff --git a/litellm/llms/openai/speech/guardrail_translation/handler.py b/litellm/llms/openai/speech/guardrail_translation/handler.py
index 4c2f71477be..e6796fbac2a 100644
--- a/litellm/llms/openai/speech/guardrail_translation/handler.py
+++ b/litellm/llms/openai/speech/guardrail_translation/handler.py
@@ -9,6 +9,7 @@ from typing import TYPE_CHECKING, Any, Optional
from litellm._logging import verbose_proxy_logger
from litellm.llms.base_llm.guardrail_translation.base_translation import BaseTranslation
+from litellm.types.utils import GenericGuardrailAPIInputs
if TYPE_CHECKING:
from litellm.integrations.custom_guardrail import CustomGuardrail
@@ -50,8 +51,13 @@ class OpenAITextToSpeechHandler(BaseTranslation):
return data
if isinstance(input_text, str):
+ inputs = GenericGuardrailAPIInputs(texts=[input_text])
+ # Include model information if available (voice model)
+ model = data.get("model")
+ if model:
+ inputs["model"] = model
guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
- inputs={"texts": [input_text]},
+ inputs=inputs,
request_data=data,
input_type="request",
logging_obj=litellm_logging_obj,
diff --git a/litellm/llms/openai/transcriptions/guardrail_translation/handler.py b/litellm/llms/openai/transcriptions/guardrail_translation/handler.py
index ac416f42c81..3d76a21c389 100644
--- a/litellm/llms/openai/transcriptions/guardrail_translation/handler.py
+++ b/litellm/llms/openai/transcriptions/guardrail_translation/handler.py
@@ -9,6 +9,7 @@ from typing import TYPE_CHECKING, Any, Optional
from litellm._logging import verbose_proxy_logger
from litellm.llms.base_llm.guardrail_translation.base_translation import BaseTranslation
+from litellm.types.utils import GenericGuardrailAPIInputs
if TYPE_CHECKING:
from litellm.integrations.custom_guardrail import CustomGuardrail
@@ -88,8 +89,12 @@ class OpenAIAudioTranscriptionHandler(BaseTranslation):
if user_metadata:
request_data["litellm_metadata"] = user_metadata
+ inputs = GenericGuardrailAPIInputs(texts=[original_text])
+ # Include model information from the response if available
+ if hasattr(response, "model") and response.model:
+ inputs["model"] = response.model
guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
- inputs={"texts": [original_text]},
+ inputs=inputs,
request_data=request_data,
input_type="response",
logging_obj=litellm_logging_obj,
diff --git a/litellm/llms/openai_like/embedding/handler.py b/litellm/llms/openai_like/embedding/handler.py
index 95a4aa854ad..d0d26d5959f 100644
--- a/litellm/llms/openai_like/embedding/handler.py
+++ b/litellm/llms/openai_like/embedding/handler.py
@@ -105,7 +105,8 @@ class OpenAILikeEmbeddingHandler(OpenAILikeBase):
custom_endpoint=custom_endpoint,
)
model = model
- data = {"model": model, "input": input, **optional_params}
+ filtered_optional_params = {k: v for k, v in optional_params.items() if v not in (None, '')}
+ data = {"model": model, "input": input, **filtered_optional_params}
## LOGGING
logging_obj.pre_call(
diff --git a/litellm/llms/openrouter/chat/transformation.py b/litellm/llms/openrouter/chat/transformation.py
index b5610852fd2..e3770dbbf49 100644
--- a/litellm/llms/openrouter/chat/transformation.py
+++ b/litellm/llms/openrouter/chat/transformation.py
@@ -26,6 +26,9 @@ class CacheControlSupportedModels(str, Enum):
"""Models that support cache_control in content blocks."""
CLAUDE = "claude"
GEMINI = "gemini"
+ MINIMAX = "minimax"
+ GLM = "glm"
+ ZAI = "z-ai"
class OpenrouterConfig(OpenAIGPTConfig):
@@ -39,6 +42,7 @@ class OpenrouterConfig(OpenAIGPTConfig):
model=model, custom_llm_provider="openrouter"
) or litellm.supports_reasoning(model=model):
supported_params.append("reasoning_effort")
+ supported_params.append("thinking")
except Exception:
pass
return list(dict.fromkeys(supported_params))
diff --git a/litellm/llms/pass_through/guardrail_translation/handler.py b/litellm/llms/pass_through/guardrail_translation/handler.py
index c0979e37e66..40433d53413 100644
--- a/litellm/llms/pass_through/guardrail_translation/handler.py
+++ b/litellm/llms/pass_through/guardrail_translation/handler.py
@@ -11,6 +11,7 @@ from typing import TYPE_CHECKING, Any, List, Optional
from litellm._logging import verbose_proxy_logger
from litellm.llms.base_llm.guardrail_translation.base_translation import BaseTranslation
from litellm.proxy._types import PassThroughGuardrailSettings
+from litellm.types.utils import GenericGuardrailAPIInputs
if TYPE_CHECKING:
from litellm.integrations.custom_guardrail import CustomGuardrail
@@ -118,8 +119,13 @@ class PassThroughEndpointHandler(BaseTranslation):
return data
# Apply guardrail (pass-through doesn't modify the text, just checks it)
+ inputs = GenericGuardrailAPIInputs(texts=[text_to_check])
+ # Include model information if available
+ model = data.get("model")
+ if model:
+ inputs["model"] = model
_guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
- inputs={"texts": [text_to_check]},
+ inputs=inputs,
request_data=data,
input_type="request",
logging_obj=litellm_logging_obj,
@@ -178,8 +184,13 @@ class PassThroughEndpointHandler(BaseTranslation):
request_data["litellm_metadata"] = user_metadata
# Apply guardrail (pass-through doesn't modify the text, just checks it)
+ inputs = GenericGuardrailAPIInputs(texts=[text_to_check])
+ # Include model information from the response if available
+ response_model = response.get("model") if isinstance(response, dict) else None
+ if response_model:
+ inputs["model"] = response_model
_guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
- inputs={"texts": [text_to_check]},
+ inputs=inputs,
request_data=request_data,
input_type="response",
logging_obj=litellm_logging_obj,
diff --git a/litellm/llms/s3_vectors/__init__.py b/litellm/llms/s3_vectors/__init__.py
new file mode 100644
index 00000000000..e8367949c3e
--- /dev/null
+++ b/litellm/llms/s3_vectors/__init__.py
@@ -0,0 +1 @@
+# S3 Vectors LLM integration
diff --git a/litellm/llms/s3_vectors/vector_stores/__init__.py b/litellm/llms/s3_vectors/vector_stores/__init__.py
new file mode 100644
index 00000000000..ac24b4a38da
--- /dev/null
+++ b/litellm/llms/s3_vectors/vector_stores/__init__.py
@@ -0,0 +1 @@
+# S3 Vectors vector store integration
diff --git a/litellm/llms/s3_vectors/vector_stores/transformation.py b/litellm/llms/s3_vectors/vector_stores/transformation.py
new file mode 100644
index 00000000000..df81a78289a
--- /dev/null
+++ b/litellm/llms/s3_vectors/vector_stores/transformation.py
@@ -0,0 +1,254 @@
+from typing import TYPE_CHECKING, Any, Dict, List, Optional, Tuple, Union
+
+import httpx
+
+from litellm.llms.base_llm.vector_store.transformation import BaseVectorStoreConfig
+from litellm.llms.bedrock.base_aws_llm import BaseAWSLLM
+from litellm.types.router import GenericLiteLLMParams
+from litellm.types.vector_stores import (
+ VECTOR_STORE_OPENAI_PARAMS,
+ BaseVectorStoreAuthCredentials,
+ VectorStoreIndexEndpoints,
+ VectorStoreResultContent,
+ VectorStoreSearchOptionalRequestParams,
+ VectorStoreSearchResponse,
+ VectorStoreSearchResult,
+)
+
+if TYPE_CHECKING:
+ from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj
+else:
+ LiteLLMLoggingObj = Any
+
+
+class S3VectorsVectorStoreConfig(BaseVectorStoreConfig, BaseAWSLLM):
+ """Vector store configuration for AWS S3 Vectors."""
+
+ def __init__(self) -> None:
+ BaseVectorStoreConfig.__init__(self)
+ BaseAWSLLM.__init__(self)
+
+ def get_auth_credentials(
+ self, litellm_params: dict
+ ) -> BaseVectorStoreAuthCredentials:
+ return {}
+
+ def get_vector_store_endpoints_by_type(self) -> VectorStoreIndexEndpoints:
+ return {
+ "read": [("POST", "/QueryVectors")],
+ "write": [],
+ }
+
+ def get_supported_openai_params(
+ self, model: str
+ ) -> List[VECTOR_STORE_OPENAI_PARAMS]:
+ return ["max_num_results"]
+
+ def map_openai_params(
+ self,
+ non_default_params: dict,
+ optional_params: dict,
+ drop_params: bool,
+ ) -> dict:
+ for param, value in non_default_params.items():
+ if param == "max_num_results":
+ optional_params["maxResults"] = value
+ return optional_params
+
+ def validate_environment(
+ self, headers: dict, litellm_params: Optional[GenericLiteLLMParams]
+ ) -> dict:
+ headers = headers or {}
+ headers.setdefault("Content-Type", "application/json")
+ return headers
+
+ def get_complete_url(self, api_base: Optional[str], litellm_params: dict) -> str:
+ aws_region_name = litellm_params.get("aws_region_name")
+ if not aws_region_name:
+ raise ValueError("aws_region_name is required for S3 Vectors")
+ return f"https://s3vectors.{aws_region_name}.api.aws"
+
+ def transform_search_vector_store_request(
+ self,
+ vector_store_id: str,
+ query: Union[str, List[str]],
+ vector_store_search_optional_params: VectorStoreSearchOptionalRequestParams,
+ api_base: str,
+ litellm_logging_obj: LiteLLMLoggingObj,
+ litellm_params: dict,
+ ) -> Tuple[str, Dict]:
+ """Sync version - generates embedding synchronously."""
+ # For S3 Vectors, vector_store_id should be in format: bucket_name:index_name
+ # If not in that format, try to construct it from litellm_params
+ bucket_name: str
+ index_name: str
+
+ if ":" in vector_store_id:
+ bucket_name, index_name = vector_store_id.split(":", 1)
+ else:
+ # Try to get bucket_name from litellm_params
+ bucket_name_from_params = litellm_params.get("vector_bucket_name")
+ if not bucket_name_from_params or not isinstance(bucket_name_from_params, str):
+ raise ValueError(
+ "vector_store_id must be in format 'bucket_name:index_name' for S3 Vectors, "
+ "or vector_bucket_name must be provided in litellm_params"
+ )
+ bucket_name = bucket_name_from_params
+ index_name = vector_store_id
+
+ if isinstance(query, list):
+ query = " ".join(query)
+
+ # Generate embedding for the query
+ embedding_model = litellm_params.get("embedding_model", "text-embedding-3-small")
+
+ import litellm as litellm_module
+ embedding_response = litellm_module.embedding(model=embedding_model, input=[query])
+ query_embedding = embedding_response.data[0]["embedding"]
+
+ url = f"{api_base}/QueryVectors"
+
+ request_body: Dict[str, Any] = {
+ "vectorBucketName": bucket_name,
+ "indexName": index_name,
+ "queryVector": {"float32": query_embedding},
+ "topK": vector_store_search_optional_params.get("max_num_results", 5), # Default to 5
+ "returnDistance": True,
+ "returnMetadata": True,
+ }
+
+ litellm_logging_obj.model_call_details["query"] = query
+ return url, request_body
+
+ async def atransform_search_vector_store_request(
+ self,
+ vector_store_id: str,
+ query: Union[str, List[str]],
+ vector_store_search_optional_params: VectorStoreSearchOptionalRequestParams,
+ api_base: str,
+ litellm_logging_obj: LiteLLMLoggingObj,
+ litellm_params: dict,
+ ) -> Tuple[str, Dict]:
+ """Async version - generates embedding asynchronously."""
+ # For S3 Vectors, vector_store_id should be in format: bucket_name:index_name
+ # If not in that format, try to construct it from litellm_params
+ bucket_name: str
+ index_name: str
+
+ if ":" in vector_store_id:
+ bucket_name, index_name = vector_store_id.split(":", 1)
+ else:
+ # Try to get bucket_name from litellm_params
+ bucket_name_from_params = litellm_params.get("vector_bucket_name")
+ if not bucket_name_from_params or not isinstance(bucket_name_from_params, str):
+ raise ValueError(
+ "vector_store_id must be in format 'bucket_name:index_name' for S3 Vectors, "
+ "or vector_bucket_name must be provided in litellm_params"
+ )
+ bucket_name = bucket_name_from_params
+ index_name = vector_store_id
+
+ if isinstance(query, list):
+ query = " ".join(query)
+
+ # Generate embedding for the query asynchronously
+ embedding_model = litellm_params.get("embedding_model", "text-embedding-3-small")
+
+ import litellm as litellm_module
+ embedding_response = await litellm_module.aembedding(model=embedding_model, input=[query])
+ query_embedding = embedding_response.data[0]["embedding"]
+
+ url = f"{api_base}/QueryVectors"
+
+ request_body: Dict[str, Any] = {
+ "vectorBucketName": bucket_name,
+ "indexName": index_name,
+ "queryVector": {"float32": query_embedding},
+ "topK": vector_store_search_optional_params.get("max_num_results", 5), # Default to 5
+ "returnDistance": True,
+ "returnMetadata": True,
+ }
+
+ litellm_logging_obj.model_call_details["query"] = query
+ return url, request_body
+
+ def sign_request(
+ self,
+ headers: dict,
+ optional_params: Dict,
+ request_data: Dict,
+ api_base: str,
+ api_key: Optional[str] = None,
+ ) -> Tuple[dict, Optional[bytes]]:
+ return self._sign_request(
+ service_name="s3vectors",
+ headers=headers,
+ optional_params=optional_params,
+ request_data=request_data,
+ api_base=api_base,
+ api_key=api_key,
+ )
+
+ def transform_search_vector_store_response(
+ self, response: httpx.Response, litellm_logging_obj: LiteLLMLoggingObj
+ ) -> VectorStoreSearchResponse:
+ try:
+ response_data = response.json()
+ results: List[VectorStoreSearchResult] = []
+
+ for item in response_data.get("vectors", []) or []:
+ metadata = item.get("metadata", {}) or {}
+ source_text = metadata.get("source_text", "")
+
+ if not source_text:
+ continue
+
+ # Extract file information from metadata
+ chunk_index = metadata.get("chunk_index", "0")
+ file_id = f"s3-vectors-chunk-{chunk_index}"
+ filename = metadata.get("filename", f"document-{chunk_index}")
+
+ # S3 Vectors returns distance, convert to similarity score (0-1)
+ # Lower distance = higher similarity
+ # We'll normalize using 1 / (1 + distance) to get a 0-1 score
+ distance = item.get("distance")
+ score = None
+ if distance is not None:
+ # Convert distance to similarity score between 0 and 1
+ # For cosine distance: similarity = 1 - distance
+ # For euclidean: use 1 / (1 + distance)
+ # Assuming cosine distance here
+ score = max(0.0, min(1.0, 1.0 - float(distance)))
+
+ results.append(
+ VectorStoreSearchResult(
+ score=score,
+ content=[VectorStoreResultContent(text=source_text, type="text")],
+ file_id=file_id,
+ filename=filename,
+ attributes=metadata,
+ )
+ )
+
+ return VectorStoreSearchResponse(
+ object="vector_store.search_results.page",
+ search_query=litellm_logging_obj.model_call_details.get("query", ""),
+ data=results,
+ )
+ except Exception as e:
+ raise self.get_error_class(
+ error_message=str(e),
+ status_code=response.status_code,
+ headers=response.headers,
+ )
+
+ # Vector store creation is not yet implemented
+ def transform_create_vector_store_request(
+ self,
+ vector_store_create_optional_params,
+ api_base: str,
+ ) -> Tuple[str, Dict]:
+ raise NotImplementedError
+
+ def transform_create_vector_store_response(self, response: httpx.Response):
+ raise NotImplementedError
diff --git a/litellm/llms/vercel_ai_gateway/embedding/__init__.py b/litellm/llms/vercel_ai_gateway/embedding/__init__.py
new file mode 100644
index 00000000000..e69de29bb2d
diff --git a/litellm/llms/vercel_ai_gateway/embedding/transformation.py b/litellm/llms/vercel_ai_gateway/embedding/transformation.py
new file mode 100644
index 00000000000..7238b05f10d
--- /dev/null
+++ b/litellm/llms/vercel_ai_gateway/embedding/transformation.py
@@ -0,0 +1,176 @@
+"""
+Vercel AI Gateway Embedding API Configuration.
+
+This module provides the configuration for Vercel AI Gateway's Embedding API.
+Vercel AI Gateway is OpenAI-compatible and supports embeddings via the /v1/embeddings endpoint.
+
+Docs: https://vercel.com/docs/ai-gateway/openai-compat/embeddings
+"""
+
+from typing import TYPE_CHECKING, Any, Optional
+
+import httpx
+
+from litellm.llms.base_llm.embedding.transformation import BaseEmbeddingConfig
+from litellm.secret_managers.main import get_secret_str
+from litellm.types.llms.openai import AllEmbeddingInputValues
+from litellm.types.utils import EmbeddingResponse
+from litellm.utils import convert_to_model_response_object
+
+from ..common_utils import VercelAIGatewayException
+
+if TYPE_CHECKING:
+ from litellm.litellm_core_utils.litellm_logging import Logging as _LiteLLMLoggingObj
+
+ LiteLLMLoggingObj = _LiteLLMLoggingObj
+else:
+ LiteLLMLoggingObj = Any
+
+
+class VercelAIGatewayEmbeddingConfig(BaseEmbeddingConfig):
+ """
+ Configuration for Vercel AI Gateway's Embedding API.
+
+ Reference: https://vercel.com/docs/ai-gateway/openai-compat/embeddings
+ """
+
+ def validate_environment(
+ self,
+ headers: dict,
+ model: str,
+ messages: list,
+ optional_params: dict,
+ litellm_params: dict,
+ api_key: Optional[str] = None,
+ api_base: Optional[str] = None,
+ ) -> dict:
+ """
+ Validate environment and set up headers for Vercel AI Gateway API.
+
+ Vercel AI Gateway requires:
+ - Authorization header with Bearer token (API key or OIDC token)
+ """
+ vercel_headers = {
+ "Content-Type": "application/json",
+ }
+
+ # Add Authorization header if api_key is provided
+ if api_key:
+ vercel_headers["Authorization"] = f"Bearer {api_key}"
+
+ # Merge with existing headers (user's extra_headers take priority)
+ merged_headers = {**vercel_headers, **headers}
+
+ return merged_headers
+
+ def get_complete_url(
+ self,
+ api_base: Optional[str],
+ api_key: Optional[str],
+ model: str,
+ optional_params: dict,
+ litellm_params: dict,
+ stream: Optional[bool] = None,
+ ) -> str:
+ """
+ Get the complete URL for Vercel AI Gateway Embedding API endpoint.
+ """
+ if api_base:
+ api_base = api_base.rstrip("/")
+ else:
+ api_base = (
+ get_secret_str("VERCEL_AI_GATEWAY_API_BASE")
+ or "https://ai-gateway.vercel.sh/v1"
+ )
+
+ return f"{api_base}/embeddings"
+
+ def transform_embedding_request(
+ self,
+ model: str,
+ input: AllEmbeddingInputValues,
+ optional_params: dict,
+ headers: dict,
+ ) -> dict:
+ """
+ Transform embedding request to Vercel AI Gateway format (OpenAI-compatible).
+ """
+ # Ensure input is a list
+ if isinstance(input, str):
+ input = [input]
+
+ # Strip 'vercel_ai_gateway/' prefix if present
+ if model.startswith("vercel_ai_gateway/"):
+ model = model.replace("vercel_ai_gateway/", "", 1)
+
+ return {
+ "model": model,
+ "input": input,
+ **optional_params,
+ }
+
+ def transform_embedding_response(
+ self,
+ model: str,
+ raw_response: httpx.Response,
+ model_response: EmbeddingResponse,
+ logging_obj: LiteLLMLoggingObj,
+ api_key: Optional[str],
+ request_data: dict,
+ optional_params: dict,
+ litellm_params: dict,
+ ) -> EmbeddingResponse:
+ """
+ Transform embedding response from Vercel AI Gateway format (OpenAI-compatible).
+ """
+ logging_obj.post_call(original_response=raw_response.text)
+
+ # Vercel AI Gateway returns standard OpenAI-compatible embedding response
+ response_json = raw_response.json()
+
+ return convert_to_model_response_object(
+ response_object=response_json,
+ model_response_object=model_response,
+ response_type="embedding",
+ )
+
+ def get_supported_openai_params(self, model: str) -> list:
+ """
+ Get list of supported OpenAI parameters for Vercel AI Gateway embeddings.
+
+ Vercel AI Gateway supports the standard OpenAI embeddings parameters
+ and auto-maps 'dimensions' to each provider's expected field.
+ """
+ return [
+ "timeout",
+ "dimensions",
+ "encoding_format",
+ "user",
+ ]
+
+ def map_openai_params(
+ self,
+ non_default_params: dict,
+ optional_params: dict,
+ model: str,
+ drop_params: bool,
+ ) -> dict:
+ """
+ Map OpenAI parameters to Vercel AI Gateway format.
+ """
+ for param, value in non_default_params.items():
+ if param in self.get_supported_openai_params(model):
+ optional_params[param] = value
+ return optional_params
+
+ def get_error_class(
+ self, error_message: str, status_code: int, headers: Any
+ ) -> Any:
+ """
+ Get the error class for Vercel AI Gateway errors.
+ """
+ return VercelAIGatewayException(
+ message=error_message,
+ status_code=status_code,
+ headers=headers,
+ )
diff --git a/litellm/llms/vertex_ai/common_utils.py b/litellm/llms/vertex_ai/common_utils.py
index 152b99ca4db..a0e2ddf5e98 100644
--- a/litellm/llms/vertex_ai/common_utils.py
+++ b/litellm/llms/vertex_ai/common_utils.py
@@ -849,7 +849,7 @@ def get_vertex_model_id_from_url(url: str) -> Optional[str]:
`https://${LOCATION}-aiplatform.googleapis.com/v1/projects/${PROJECT_ID}/locations/${LOCATION}/publishers/google/models/${MODEL_ID}:streamGenerateContent`
"""
- match = re.search(r"/models/([^/:]+)", url)
+ match = re.search(r"/models/([^:]+)", url)
return match.group(1) if match else None
diff --git a/litellm/llms/vertex_ai/context_caching/vertex_ai_context_caching.py b/litellm/llms/vertex_ai/context_caching/vertex_ai_context_caching.py
index 289963e917a..ed4d2d6a740 100644
--- a/litellm/llms/vertex_ai/context_caching/vertex_ai_context_caching.py
+++ b/litellm/llms/vertex_ai/context_caching/vertex_ai_context_caching.py
@@ -27,6 +27,8 @@ local_cache_obj = Cache(
type=LiteLLMCacheType.LOCAL
) # only used for calling 'get_cache_key' function
+MAX_PAGINATION_PAGES = 100 # Reasonable upper bound for pagination
+
class ContextCachingEndpoints(VertexBase):
"""
@@ -115,7 +117,7 @@ class ContextCachingEndpoints(VertexBase):
- None
"""
- _, url = self._get_token_and_url_context_caching(
+ _, base_url = self._get_token_and_url_context_caching(
gemini_api_key=api_key,
custom_llm_provider=custom_llm_provider,
api_base=api_base,
@@ -123,43 +125,63 @@ class ContextCachingEndpoints(VertexBase):
vertex_location=vertex_location,
vertex_auth_header=vertex_auth_header
)
- try:
- ## LOGGING
- logging_obj.pre_call(
- input="",
- api_key="",
- additional_args={
- "complete_input_dict": {},
- "api_base": url,
- "headers": headers,
- },
- )
- resp = client.get(url=url, headers=headers)
- resp.raise_for_status()
- except httpx.HTTPStatusError as e:
- if e.response.status_code == 403:
+ page_token: Optional[str] = None
+
+ # Iterate through all pages
+ for _ in range(MAX_PAGINATION_PAGES):
+ # Build URL with pagination token if present
+ if page_token:
+ separator = "&" if "?" in base_url else "?"
+ url = f"{base_url}{separator}pageToken={page_token}"
+ else:
+ url = base_url
+
+ try:
+ ## LOGGING
+ logging_obj.pre_call(
+ input="",
+ api_key="",
+ additional_args={
+ "complete_input_dict": {},
+ "api_base": url,
+ "headers": headers,
+ },
+ )
+
+ resp = client.get(url=url, headers=headers)
+ resp.raise_for_status()
+ except httpx.HTTPStatusError as e:
+ if e.response.status_code == 403:
+ return None
+ raise VertexAIError(
+ status_code=e.response.status_code, message=e.response.text
+ )
+ except Exception as e:
+ raise VertexAIError(status_code=500, message=str(e))
+
+ raw_response = resp.json()
+ logging_obj.post_call(original_response=raw_response)
+
+ if "cachedContents" not in raw_response:
return None
- raise VertexAIError(
- status_code=e.response.status_code, message=e.response.text
- )
- except Exception as e:
- raise VertexAIError(status_code=500, message=str(e))
- raw_response = resp.json()
- logging_obj.post_call(original_response=raw_response)
- if "cachedContents" not in raw_response:
- return None
+ all_cached_items = CachedContentListAllResponseBody(**raw_response)
- all_cached_items = CachedContentListAllResponseBody(**raw_response)
+ if "cachedContents" not in all_cached_items:
+ return None
- if "cachedContents" not in all_cached_items:
- return None
+ # Check current page for matching cache_key
+ for cached_item in all_cached_items["cachedContents"]:
+ display_name = cached_item.get("displayName")
+ if display_name is not None and display_name == cache_key:
+ return cached_item.get("name")
- for cached_item in all_cached_items["cachedContents"]:
- display_name = cached_item.get("displayName")
- if display_name is not None and display_name == cache_key:
- return cached_item.get("name")
+ # Check if there are more pages
+ page_token = all_cached_items.get("nextPageToken")
+ if not page_token:
+ # No more pages, cache not found
+ break
return None
@@ -187,7 +209,7 @@ class ContextCachingEndpoints(VertexBase):
- None
"""
- _, url = self._get_token_and_url_context_caching(
+ _, base_url = self._get_token_and_url_context_caching(
gemini_api_key=api_key,
custom_llm_provider=custom_llm_provider,
api_base=api_base,
@@ -195,43 +217,63 @@ class ContextCachingEndpoints(VertexBase):
vertex_location=vertex_location,
vertex_auth_header=vertex_auth_header
)
- try:
- ## LOGGING
- logging_obj.pre_call(
- input="",
- api_key="",
- additional_args={
- "complete_input_dict": {},
- "api_base": url,
- "headers": headers,
- },
- )
- resp = await client.get(url=url, headers=headers)
- resp.raise_for_status()
- except httpx.HTTPStatusError as e:
- if e.response.status_code == 403:
+ page_token: Optional[str] = None
+
+ # Iterate through all pages
+ for _ in range(MAX_PAGINATION_PAGES):
+ # Build URL with pagination token if present
+ if page_token:
+ separator = "&" if "?" in base_url else "?"
+ url = f"{base_url}{separator}pageToken={page_token}"
+ else:
+ url = base_url
+
+ try:
+ ## LOGGING
+ logging_obj.pre_call(
+ input="",
+ api_key="",
+ additional_args={
+ "complete_input_dict": {},
+ "api_base": url,
+ "headers": headers,
+ },
+ )
+
+ resp = await client.get(url=url, headers=headers)
+ resp.raise_for_status()
+ except httpx.HTTPStatusError as e:
+ if e.response.status_code == 403:
+ return None
+ raise VertexAIError(
+ status_code=e.response.status_code, message=e.response.text
+ )
+ except Exception as e:
+ raise VertexAIError(status_code=500, message=str(e))
+
+ raw_response = resp.json()
+ logging_obj.post_call(original_response=raw_response)
+
+ if "cachedContents" not in raw_response:
return None
- raise VertexAIError(
- status_code=e.response.status_code, message=e.response.text
- )
- except Exception as e:
- raise VertexAIError(status_code=500, message=str(e))
- raw_response = resp.json()
- logging_obj.post_call(original_response=raw_response)
- if "cachedContents" not in raw_response:
- return None
+ all_cached_items = CachedContentListAllResponseBody(**raw_response)
- all_cached_items = CachedContentListAllResponseBody(**raw_response)
+ if "cachedContents" not in all_cached_items:
+ return None
- if "cachedContents" not in all_cached_items:
- return None
+ # Check current page for matching cache_key
+ for cached_item in all_cached_items["cachedContents"]:
+ display_name = cached_item.get("displayName")
+ if display_name is not None and display_name == cache_key:
+ return cached_item.get("name")
- for cached_item in all_cached_items["cachedContents"]:
- display_name = cached_item.get("displayName")
- if display_name is not None and display_name == cache_key:
- return cached_item.get("name")
+ # Check if there are more pages
+ page_token = all_cached_items.get("nextPageToken")
+ if not page_token:
+ # No more pages, cache not found
+ break
return None
@@ -501,4 +543,4 @@ class ContextCachingEndpoints(VertexBase):
pass
async def async_get_cache(self):
- pass
+ pass
\ No newline at end of file
diff --git a/litellm/llms/vertex_ai/files/transformation.py b/litellm/llms/vertex_ai/files/transformation.py
index b3612113ec2..2470c59bbac 100644
--- a/litellm/llms/vertex_ai/files/transformation.py
+++ b/litellm/llms/vertex_ai/files/transformation.py
@@ -165,7 +165,7 @@ class VertexAIFilesConfig(VertexBase, BaseFilesConfig):
"""
Get the complete url for the request
"""
- bucket_name = litellm_params.get("bucket_name") or os.getenv("GCS_BUCKET_NAME")
+ bucket_name = litellm_params.get("bucket_name") or litellm_params.get("litellm_metadata", {}).pop("gcs_bucket_name", None) or os.getenv("GCS_BUCKET_NAME")
if not bucket_name:
raise ValueError("GCS bucket_name is required")
file_data = data.get("file")
diff --git a/litellm/llms/vertex_ai/gemini/vertex_and_google_ai_studio_gemini.py b/litellm/llms/vertex_ai/gemini/vertex_and_google_ai_studio_gemini.py
index b78ac8f9e98..04ae4b6beb8 100644
--- a/litellm/llms/vertex_ai/gemini/vertex_and_google_ai_studio_gemini.py
+++ b/litellm/llms/vertex_ai/gemini/vertex_and_google_ai_studio_gemini.py
@@ -478,6 +478,13 @@ class VertexGeminiConfig(VertexAIBaseConfig, BaseConfig):
if "type" in tool and tool["type"] == "computer_use":
computer_use_config = {k: v for k, v in tool.items() if k != "type"}
tool = {VertexToolName.COMPUTER_USE.value: computer_use_config}
+ # Handle OpenAI-style web_search and web_search_preview tools
+ # Transform them to Gemini's googleSearch tool
+ elif "type" in tool and tool["type"] in ("web_search", "web_search_preview"):
+ verbose_logger.info(
+ f"Gemini: Transforming OpenAI-style '{tool['type']}' tool to googleSearch"
+ )
+ tool = {VertexToolName.GOOGLE_SEARCH.value: {}}
# Handle tools with 'type' field (OpenAI spec compliance) Ignore this field -> https://github.com/BerriAI/litellm/issues/14644#issuecomment-3342061838
elif "type" in tool:
tool = {k: tool[k] for k in tool if k != "type"}
@@ -1657,7 +1664,17 @@ class VertexGeminiConfig(VertexAIBaseConfig, BaseConfig):
## This is necessary because promptTokensDetails includes both cached and non-cached tokens
## See: https://github.com/BerriAI/litellm/issues/18750
if cached_text_tokens is not None and prompt_text_tokens is not None:
+ # Explicit caching: subtract cached tokens per modality from cacheTokensDetails
prompt_text_tokens = prompt_text_tokens - cached_text_tokens
+ elif (
+ cached_tokens is not None
+ and prompt_text_tokens is not None
+ and cached_text_tokens is None
+ ):
+ # Implicit caching: only cachedContentTokenCount is provided (no cacheTokensDetails)
+ # Subtract from text tokens since implicit caching is primarily for text content
+ # See: https://github.com/BerriAI/litellm/issues/16341
+ prompt_text_tokens = prompt_text_tokens - cached_tokens
if cached_audio_tokens is not None and prompt_audio_tokens is not None:
prompt_audio_tokens = prompt_audio_tokens - cached_audio_tokens
if cached_image_tokens is not None and prompt_image_tokens is not None:
@@ -1715,6 +1732,52 @@ class VertexGeminiConfig(VertexAIBaseConfig, BaseConfig):
else:
return "stop"
+ @staticmethod
+ def _check_prompt_level_content_filter(
+ processed_chunk: GenerateContentResponseBody,
+ response_id: Optional[str],
+ ) -> Optional["ModelResponseStream"]:
+ """
+ Check if prompt is blocked due to content filtering at the prompt level.
+
+ This handles the case where Vertex AI blocks the prompt before generation begins,
+ indicated by promptFeedback.blockReason being present.
+
+ Args:
+ processed_chunk: The parsed response chunk from Vertex AI
+ response_id: The response ID from the chunk
+
+ Returns:
+ ModelResponseStream with content_filter finish_reason if blocked, None otherwise.
+
+ Note:
+ This is consistent with non-streaming _handle_blocked_response() behavior.
+ Candidate-level content filtering (SAFETY, RECITATION, etc.) is handled
+ separately via _process_candidates() → _check_finish_reason().
+ """
+ from litellm.types.utils import Delta, ModelResponseStream, StreamingChoices
+
+ # Check if prompt is blocked due to content filtering
+ prompt_feedback = processed_chunk.get("promptFeedback")
+ if prompt_feedback and "blockReason" in prompt_feedback:
+ verbose_logger.debug(
+ f"Prompt blocked due to: {prompt_feedback.get('blockReason')} - {prompt_feedback.get('blockReasonMessage')}"
+ )
+
+ # Create a content_filter response (consistent with non-streaming _handle_blocked_response)
+ choice = StreamingChoices(
+ finish_reason="content_filter",
+ index=0,
+ delta=Delta(content=None, role="assistant"),
+ logprobs=None,
+ enhancements=None,
+ )
+
+ model_response = ModelResponseStream(choices=[choice], id=response_id)
+ return model_response
+
+ return None
+
@staticmethod
def _calculate_web_search_requests(grounding_metadata: List[dict]) -> Optional[int]:
web_search_requests: Optional[int] = None
@@ -2796,6 +2859,15 @@ class ModelResponseIterator:
processed_chunk = GenerateContentResponseBody(**chunk) # type: ignore
response_id = processed_chunk.get("responseId")
model_response = ModelResponseStream(choices=[], id=response_id)
+
+ # Check if prompt is blocked due to content filtering
+ blocked_response = VertexGeminiConfig._check_prompt_level_content_filter(
+ processed_chunk=processed_chunk,
+ response_id=response_id,
+ )
+ if blocked_response is not None:
+ model_response = blocked_response
+
usage: Optional[Usage] = None
_candidates: Optional[List[Candidates]] = processed_chunk.get("candidates")
grounding_metadata: List[dict] = []
diff --git a/litellm/llms/vertex_ai/image_generation/vertex_gemini_transformation.py b/litellm/llms/vertex_ai/image_generation/vertex_gemini_transformation.py
index 89ed9f1a8a5..ba3df88be14 100644
--- a/litellm/llms/vertex_ai/image_generation/vertex_gemini_transformation.py
+++ b/litellm/llms/vertex_ai/image_generation/vertex_gemini_transformation.py
@@ -295,9 +295,11 @@ class VertexAIGeminiImageGenerationConfig(BaseImageGenerationConfig, VertexLLM):
if "inlineData" in part:
inline_data = part["inlineData"]
if "data" in inline_data:
+ thought_sig = part.get("thoughtSignature")
model_response.data.append(ImageObject(
b64_json=inline_data["data"],
url=None,
+ provider_specific_fields={"thought_signature": thought_sig} if thought_sig else None,
))
if usage_metadata := response_data.get("usageMetadata", None):
diff --git a/litellm/llms/vertex_ai/vertex_ai_partner_models/anthropic/experimental_pass_through/transformation.py b/litellm/llms/vertex_ai/vertex_ai_partner_models/anthropic/experimental_pass_through/transformation.py
index fc75376c0cb..918b8ecc225 100644
--- a/litellm/llms/vertex_ai/vertex_ai_partner_models/anthropic/experimental_pass_through/transformation.py
+++ b/litellm/llms/vertex_ai/vertex_ai_partner_models/anthropic/experimental_pass_through/transformation.py
@@ -1,5 +1,8 @@
from typing import Any, Dict, List, Optional, Tuple
+from litellm.anthropic_beta_headers_manager import (
+ update_headers_with_filtered_beta,
+)
from litellm.llms.anthropic.common_utils import AnthropicModelInfo
from litellm.llms.anthropic.experimental_pass_through.messages.transformation import (
AnthropicMessagesConfig,
@@ -64,7 +67,7 @@ class VertexAIPartnerModelsAnthropicMessagesConfig(AnthropicMessagesConfig, Vert
existing_beta = headers.get("anthropic-beta")
if existing_beta:
beta_values.update(b.strip() for b in existing_beta.split(","))
-
+
# Check for web search tool
for tool in tools:
if isinstance(tool, dict) and tool.get("type", "").startswith(ANTHROPIC_HOSTED_TOOLS.WEB_SEARCH.value):
@@ -79,6 +82,12 @@ class VertexAIPartnerModelsAnthropicMessagesConfig(AnthropicMessagesConfig, Vert
if beta_values:
headers["anthropic-beta"] = ",".join(beta_values)
+ # Filter out unsupported beta headers for Vertex AI
+ headers = update_headers_with_filtered_beta(
+ headers=headers,
+ provider="vertex_ai",
+ )
+
return headers, api_base
def get_complete_url(
diff --git a/litellm/llms/vertex_ai/vertex_ai_partner_models/anthropic/transformation.py b/litellm/llms/vertex_ai/vertex_ai_partner_models/anthropic/transformation.py
index 1df07f405e6..0b728d88e76 100644
--- a/litellm/llms/vertex_ai/vertex_ai_partner_models/anthropic/transformation.py
+++ b/litellm/llms/vertex_ai/vertex_ai_partner_models/anthropic/transformation.py
@@ -51,6 +51,40 @@ class VertexAIAnthropicConfig(AnthropicConfig):
def custom_llm_provider(self) -> Optional[str]:
return "vertex_ai"
+ def _add_context_management_beta_headers(
+ self, beta_set: set, context_management: dict
+ ) -> None:
+ """
+ Add context_management beta headers to the beta_set.
+
+ - If any edit has type "compact_20260112", add compact-2026-01-12 header
+ - For all other edits, add context-management-2025-06-27 header
+
+ Args:
+ beta_set: Set of beta headers to modify in-place
+ context_management: The context_management dict from optional_params
+ """
+ from litellm.types.llms.anthropic import ANTHROPIC_BETA_HEADER_VALUES
+
+ edits = context_management.get("edits", [])
+ has_compact = False
+ has_other = False
+
+ for edit in edits:
+ edit_type = edit.get("type", "")
+ if edit_type == "compact_20260112":
+ has_compact = True
+ else:
+ has_other = True
+
+ # Add compact header if any compact edits exist
+ if has_compact:
+ beta_set.add(ANTHROPIC_BETA_HEADER_VALUES.COMPACT_2026_01_12.value)
+
+ # Add context management header if any other edits exist
+ if has_other:
+ beta_set.add(ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value)
+
def transform_request(
self,
model: str,
@@ -86,6 +120,11 @@ class VertexAIAnthropicConfig(AnthropicConfig):
beta_set = set(auto_betas)
if tool_search_used:
beta_set.add("tool-search-tool-2025-10-19") # Vertex requires this header for tool search
+
+ # Add context_management beta headers (compact and/or context-management)
+ context_management = optional_params.get("context_management")
+ if context_management:
+ self._add_context_management_beta_headers(beta_set, context_management)
if beta_set:
data["anthropic_beta"] = list(beta_set)
diff --git a/litellm/llms/vertex_ai/vertex_llm_base.py b/litellm/llms/vertex_ai/vertex_llm_base.py
index a185370e376..4613b6a5715 100644
--- a/litellm/llms/vertex_ai/vertex_llm_base.py
+++ b/litellm/llms/vertex_ai/vertex_llm_base.py
@@ -20,6 +20,7 @@ from .common_utils import (
_get_vertex_url,
all_gemini_url_modes,
get_vertex_base_model_name,
+ get_vertex_base_url,
is_global_only_vertex_model,
)
@@ -200,12 +201,7 @@ class VertexBase:
) -> str:
if api_base:
return api_base
- elif vertex_location == "global":
- return "https://aiplatform.googleapis.com"
- elif vertex_location:
- return f"https://{vertex_location}-aiplatform.googleapis.com"
- else:
- return f"https://{self.get_default_vertex_location()}-aiplatform.googleapis.com"
+ return get_vertex_base_url(vertex_location or self.get_default_vertex_location())
@staticmethod
def create_vertex_url(
@@ -218,7 +214,8 @@ class VertexBase:
) -> str:
"""Return the base url for the vertex partner models"""
- api_base = api_base or f"https://{vertex_location}-aiplatform.googleapis.com"
+ if api_base is None:
+ api_base = get_vertex_base_url(vertex_location)
if partner == VertexPartnerProvider.llama:
return f"{api_base}/v1/projects/{vertex_project}/locations/{vertex_location}/endpoints/openapi/chat/completions"
elif partner == VertexPartnerProvider.mistralai:
@@ -247,11 +244,13 @@ class VertexBase:
stream: Optional[bool],
model: str,
) -> str:
+ # Use get_vertex_region to handle global-only models
+ resolved_location = self.get_vertex_region(vertex_location, model)
api_base = self.get_api_base(
- api_base=custom_api_base, vertex_location=vertex_location
+ api_base=custom_api_base, vertex_location=resolved_location
)
default_api_base = VertexBase.create_vertex_url(
- vertex_location=vertex_location or "us-central1",
+ vertex_location=resolved_location,
vertex_project=vertex_project or project_id,
partner=partner,
stream=stream,
@@ -274,7 +273,7 @@ class VertexBase:
url=default_api_base,
model=model,
vertex_project=vertex_project or project_id,
- vertex_location=vertex_location or "us-central1",
+ vertex_location=resolved_location,
vertex_api_version="v1", # Partner models typically use v1
)
return api_base
diff --git a/litellm/llms/watsonx/common_utils.py b/litellm/llms/watsonx/common_utils.py
index 774f6dc1f3d..230c9f4cf6e 100644
--- a/litellm/llms/watsonx/common_utils.py
+++ b/litellm/llms/watsonx/common_utils.py
@@ -42,6 +42,7 @@ def generate_iam_token(api_key=None, **params) -> str:
get_secret_str("WX_API_KEY")
or get_secret_str("WATSONX_API_KEY")
or get_secret_str("WATSONX_APIKEY")
+ or get_secret_str("WATSONX_ZENAPIKEY")
)
if api_key is None:
raise ValueError("API key is required")
@@ -319,6 +320,7 @@ class IBMWatsonXMixin:
or get_secret_str("WATSONX_APIKEY")
or get_secret_str("WATSONX_API_KEY")
or get_secret_str("WX_API_KEY")
+ or get_secret_str("WATSONX_ZENAPIKEY")
)
api_base = (
diff --git a/litellm/llms/xai/chat/transformation.py b/litellm/llms/xai/chat/transformation.py
index 245e10e45c1..21782fc6fbf 100644
--- a/litellm/llms/xai/chat/transformation.py
+++ b/litellm/llms/xai/chat/transformation.py
@@ -4,6 +4,7 @@ import httpx
import litellm
from litellm._logging import verbose_logger
+from litellm.constants import XAI_API_BASE
from litellm.litellm_core_utils.prompt_templates.common_utils import (
filter_value_from_dict,
strip_name_from_messages,
@@ -14,8 +15,6 @@ from litellm.types.utils import Choices, ModelResponse, Usage, PromptTokensDetai
from ...openai.chat.gpt_transformation import OpenAIGPTConfig
-XAI_API_BASE = "https://api.x.ai/v1"
-
class XAIChatConfig(OpenAIGPTConfig):
@property
diff --git a/litellm/llms/xai/realtime/__init__.py b/litellm/llms/xai/realtime/__init__.py
new file mode 100644
index 00000000000..3b0d345f2c2
--- /dev/null
+++ b/litellm/llms/xai/realtime/__init__.py
@@ -0,0 +1,5 @@
+"""xAI Realtime API handler."""
+
+from .handler import XAIRealtime
+
+__all__ = ["XAIRealtime"]
diff --git a/litellm/llms/xai/realtime/handler.py b/litellm/llms/xai/realtime/handler.py
new file mode 100644
index 00000000000..c79477ba1df
--- /dev/null
+++ b/litellm/llms/xai/realtime/handler.py
@@ -0,0 +1,38 @@
+"""
+This file contains the handler for xAI's Grok Voice Agent API `/v1/realtime` endpoint.
+
+xAI's Realtime API is fully OpenAI-compatible, so we inherit from OpenAIRealtime
+and only override the configuration differences.
+
+This requires websockets, and is currently only supported on LiteLLM Proxy.
+"""
+
+from litellm.constants import XAI_API_BASE
+
+from ...openai.realtime.handler import OpenAIRealtime
+
+
+class XAIRealtime(OpenAIRealtime):
+ """
+ Handler for xAI Grok Voice Agent API.
+
+ xAI's Realtime API uses the same WebSocket protocol as OpenAI but with:
+ - Different endpoint: wss://api.x.ai/v1/realtime (via _get_default_api_base)
+ - No OpenAI-Beta header required (via _get_additional_headers)
+ - Model: grok-4-1-fast-non-reasoning
+
+ All WebSocket logic is inherited from OpenAIRealtime.
+ """
+
+ def _get_default_api_base(self) -> str:
+ """xAI uses a different API base URL."""
+ return XAI_API_BASE
+
+ def _get_additional_headers(self, api_key: str) -> dict:
+ """
+ xAI does NOT require the OpenAI-Beta header.
+ Only send Authorization header.
+ """
+ return {
+ "Authorization": f"Bearer {api_key}",
+ }
diff --git a/litellm/llms/xai/responses/transformation.py b/litellm/llms/xai/responses/transformation.py
index bd422c8d81e..95873aab846 100644
--- a/litellm/llms/xai/responses/transformation.py
+++ b/litellm/llms/xai/responses/transformation.py
@@ -1,10 +1,12 @@
-from typing import TYPE_CHECKING, Any, Dict, List, Optional
+from typing import TYPE_CHECKING, Any, Dict, List, Optional, Union
import litellm
from litellm._logging import verbose_logger
+from litellm.constants import XAI_API_BASE
from litellm.llms.openai.responses.transformation import OpenAIResponsesAPIConfig
from litellm.secret_managers.main import get_secret_str
from litellm.types.llms.openai import ResponsesAPIOptionalRequestParams
+from litellm.types.llms.xai import XAIWebSearchTool, XAIXSearchTool
from litellm.types.router import GenericLiteLLMParams
from litellm.types.utils import LlmProviders
@@ -15,8 +17,6 @@ if TYPE_CHECKING:
else:
LiteLLMLoggingObj = Any
-XAI_API_BASE = "https://api.x.ai/v1"
-
class XAIResponsesAPIConfig(OpenAIResponsesAPIConfig):
"""
@@ -49,6 +49,85 @@ class XAIResponsesAPIConfig(OpenAIResponsesAPIConfig):
return supported_params
+ def _transform_web_search_tool(self, tool: Dict[str, Any]) -> Union[XAIWebSearchTool, Dict[str, Any]]:
+ """
+ Transform web_search tool to XAI format.
+
+ XAI supports web_search with specific filters:
+ - allowed_domains (max 5)
+ - excluded_domains (max 5)
+ - enable_image_understanding
+
+ XAI does NOT support search_context_size (OpenAI-specific).
+ """
+ xai_tool: Dict[str, Any] = {"type": "web_search"}
+
+ # Remove search_context_size if present (not supported by XAI)
+ if "search_context_size" in tool:
+ verbose_logger.info(
+ "XAI does not support 'search_context_size' parameter. Removing it from web_search tool."
+ )
+
+ # Handle filters (XAI-specific structure)
+ filters = {}
+ if "allowed_domains" in tool:
+ allowed_domains = tool["allowed_domains"]
+ filters["allowed_domains"] = allowed_domains
+
+ if "excluded_domains" in tool:
+ excluded_domains = tool["excluded_domains"]
+ filters["excluded_domains"] = excluded_domains
+
+ # Add filters if any were specified
+ if filters:
+ xai_tool["filters"] = filters
+
+ # Handle enable_image_understanding (top-level in XAI format)
+ if "enable_image_understanding" in tool:
+ xai_tool["enable_image_understanding"] = tool["enable_image_understanding"]
+
+ return xai_tool
+
+ def _transform_x_search_tool(self, tool: Dict[str, Any]) -> Union[XAIXSearchTool, Dict[str, Any]]:
+ """
+ Transform x_search tool to XAI format.
+
+ XAI supports x_search with specific parameters:
+ - allowed_x_handles (max 10)
+ - excluded_x_handles (max 10)
+ - from_date (ISO8601: YYYY-MM-DD)
+ - to_date (ISO8601: YYYY-MM-DD)
+ - enable_image_understanding
+ - enable_video_understanding
+ """
+ xai_tool: Dict[str, Any] = {"type": "x_search"}
+
+ # Handle allowed_x_handles
+ if "allowed_x_handles" in tool:
+ allowed_handles = tool["allowed_x_handles"]
+ xai_tool["allowed_x_handles"] = allowed_handles
+
+ # Handle excluded_x_handles
+ if "excluded_x_handles" in tool:
+ excluded_handles = tool["excluded_x_handles"]
+ xai_tool["excluded_x_handles"] = excluded_handles
+
+ # Handle date range
+ if "from_date" in tool:
+ xai_tool["from_date"] = tool["from_date"]
+
+ if "to_date" in tool:
+ xai_tool["to_date"] = tool["to_date"]
+
+ # Handle media understanding flags
+ if "enable_image_understanding" in tool:
+ xai_tool["enable_image_understanding"] = tool["enable_image_understanding"]
+
+ if "enable_video_understanding" in tool:
+ xai_tool["enable_video_understanding"] = tool["enable_video_understanding"]
+
+ return xai_tool
+
def map_openai_params(
self,
response_api_optional_params: ResponsesAPIOptionalRequestParams,
@@ -61,7 +140,9 @@ class XAIResponsesAPIConfig(OpenAIResponsesAPIConfig):
Handles XAI-specific transformations:
1. Drops 'instructions' parameter (not supported)
2. Transforms code_interpreter tools to remove 'container' field
- 3. Sets store=false when images are detected (recommended by XAI)
+ 3. Transforms web_search tools to XAI format (removes search_context_size, adds filters)
+ 4. Transforms x_search tools to XAI format
+ 5. Sets store=false when images are detected (recommended by XAI)
"""
params = dict(response_api_optional_params)
@@ -72,7 +153,13 @@ class XAIResponsesAPIConfig(OpenAIResponsesAPIConfig):
)
params.pop("instructions")
- # Transform code_interpreter tools - remove container field
+ if "metadata" in params:
+ verbose_logger.debug(
+ "XAI Responses API does not support 'metadata' parameter. Dropping it."
+ )
+ params.pop("metadata")
+
+ # Transform tools
if "tools" in params and params["tools"]:
tools_list = params["tools"]
# Ensure tools is a list for iteration
@@ -81,15 +168,36 @@ class XAIResponsesAPIConfig(OpenAIResponsesAPIConfig):
transformed_tools: List[Any] = []
for tool in tools_list:
- if isinstance(tool, dict) and tool.get("type") == "code_interpreter":
- # XAI supports code_interpreter but doesn't use the container field
- # Keep only the type field
- verbose_logger.debug(
- "XAI: Transforming code_interpreter tool, removing container field"
- )
- transformed_tools.append({"type": "code_interpreter"})
+ if isinstance(tool, dict):
+ tool_type = tool.get("type")
+
+ if tool_type == "code_interpreter":
+ # XAI supports code_interpreter but doesn't use the container field
+ verbose_logger.debug(
+ "XAI: Transforming code_interpreter tool, removing container field"
+ )
+ transformed_tools.append({"type": "code_interpreter"})
+
+ elif tool_type == "web_search":
+ # Transform web_search to XAI format
+ verbose_logger.debug(
+ "XAI: Transforming web_search tool to XAI format"
+ )
+ transformed_tools.append(self._transform_web_search_tool(tool))
+
+ elif tool_type == "x_search":
+ # Transform x_search to XAI format
+ verbose_logger.debug(
+ "XAI: Transforming x_search tool to XAI format"
+ )
+ transformed_tools.append(self._transform_x_search_tool(tool))
+
+ else:
+ # Keep other tools as-is
+ transformed_tools.append(tool)
else:
transformed_tools.append(tool)
+
params["tools"] = transformed_tools
return params
diff --git a/litellm/llms/zai/chat/transformation.py b/litellm/llms/zai/chat/transformation.py
index 4380256f0a4..fb1d67df357 100644
--- a/litellm/llms/zai/chat/transformation.py
+++ b/litellm/llms/zai/chat/transformation.py
@@ -1,6 +1,7 @@
-from typing import Optional, Tuple
+from typing import List, Optional, Tuple
from litellm.secret_managers.main import get_secret_str
+from litellm.types.llms.openai import AllMessageValues, ChatCompletionToolParam
from ...openai.chat.gpt_transformation import OpenAIGPTConfig
@@ -19,6 +20,19 @@ class ZAIChatConfig(OpenAIGPTConfig):
dynamic_api_key = api_key or get_secret_str("ZAI_API_KEY")
return api_base, dynamic_api_key
+ def remove_cache_control_flag_from_messages_and_tools(
+ self,
+ model: str,
+ messages: List[AllMessageValues],
+ tools: Optional[List[ChatCompletionToolParam]] = None,
+ ) -> Tuple[List[AllMessageValues], Optional[List[ChatCompletionToolParam]]]:
+ """
+ Override to preserve cache_control for GLM/ZAI.
+ GLM supports cache_control - don't strip it.
+ """
+ # GLM/ZAI supports cache_control, so return messages and tools unchanged
+ return messages, tools
+
def get_supported_openai_params(self, model: str) -> list:
base_params = [
"max_tokens",
diff --git a/litellm/main.py b/litellm/main.py
index ce84c8988e0..bca023e65ec 100644
--- a/litellm/main.py
+++ b/litellm/main.py
@@ -148,7 +148,7 @@ from litellm.utils import (
validate_and_fix_openai_messages,
validate_and_fix_openai_tools,
validate_chat_completion_tool_choice,
- validate_openai_optional_params
+ validate_openai_optional_params,
)
from ._logging import verbose_logger
@@ -368,7 +368,7 @@ class AsyncCompletions:
@tracer.wrap()
@client
-async def acompletion( # noqa: PLR0915
+async def acompletion( # noqa: PLR0915
model: str,
# Optional OpenAI params: see https://platform.openai.com/docs/api-reference/chat/create
messages: List = [],
@@ -599,16 +599,8 @@ async def acompletion( # noqa: PLR0915
# Add the context to the function
ctx = contextvars.copy_context()
func_with_context = partial(ctx.run, func)
-
- if timeout is not None and isinstance(timeout, (int, float)):
- timeout_value = float(timeout)
- init_response = await asyncio.wait_for(
- loop.run_in_executor(None, func_with_context),
- timeout=timeout_value
- )
- else:
- init_response = await loop.run_in_executor(None, func_with_context)
+ init_response = await loop.run_in_executor(None, func_with_context)
if isinstance(init_response, dict) or isinstance(
init_response, ModelResponse
): ## CACHING SCENARIO
@@ -616,11 +608,7 @@ async def acompletion( # noqa: PLR0915
response = ModelResponse(**init_response)
response = init_response
elif asyncio.iscoroutine(init_response):
- if timeout is not None and isinstance(timeout, (int, float)):
- timeout_value = float(timeout)
- response = await asyncio.wait_for(init_response, timeout=timeout_value)
- else:
- response = await init_response
+ response = await init_response
else:
response = init_response # type: ignore
@@ -637,14 +625,6 @@ async def acompletion( # noqa: PLR0915
loop=loop
) # sets the logging event loop if the user does sync streaming (e.g. on proxy for sagemaker calls)
return response
- except asyncio.TimeoutError:
- custom_llm_provider = custom_llm_provider or "openai"
- from litellm.exceptions import Timeout
- raise Timeout(
- message=f"Request timed out after {timeout} seconds",
- model=model,
- llm_provider=custom_llm_provider,
- )
except Exception as e:
custom_llm_provider = custom_llm_provider or "openai"
raise exception_type(
@@ -945,6 +925,7 @@ def mock_completion(
def responses_api_bridge_check(
model: str,
custom_llm_provider: str,
+ web_search_options: Optional[OpenAIWebSearchOptions] = None,
) -> Tuple[dict, str]:
model_info: Dict[str, Any] = {}
try:
@@ -958,6 +939,10 @@ def responses_api_bridge_check(
model = model.replace("responses/", "")
mode = "responses"
model_info["mode"] = mode
+
+ if web_search_options is not None and custom_llm_provider == "xai":
+ model_info["mode"] = "responses"
+ model = model.replace("responses/", "")
except Exception as e:
verbose_logger.debug("Error getting model info: {}".format(e))
@@ -1118,7 +1103,6 @@ def completion( # type: ignore # noqa: PLR0915
# validate optional params
stop = validate_openai_optional_params(stop=stop)
-
######### unpacking kwargs #####################
args = locals()
@@ -1135,7 +1119,9 @@ def completion( # type: ignore # noqa: PLR0915
# Check if MCP tools are present (following responses pattern)
# Cast tools to Optional[Iterable[ToolParam]] for type checking
tools_for_mcp = cast(Optional[Iterable[ToolParam]], tools)
- if LiteLLM_Proxy_MCP_Handler._should_use_litellm_mcp_gateway(tools=tools_for_mcp):
+ if LiteLLM_Proxy_MCP_Handler._should_use_litellm_mcp_gateway(
+ tools=tools_for_mcp
+ ):
# Return coroutine - acompletion will await it
# completion() can return a coroutine when MCP tools are present, which acompletion() awaits
return acompletion_with_mcp( # type: ignore[return-value]
@@ -1213,6 +1199,13 @@ def completion( # type: ignore # noqa: PLR0915
headers = {}
if extra_headers is not None:
headers.update(extra_headers)
+ # Inject proxy auth headers if configured
+ if litellm.proxy_auth is not None:
+ try:
+ proxy_headers = litellm.proxy_auth.get_auth_headers()
+ headers.update(proxy_headers)
+ except Exception as e:
+ verbose_logger.warning(f"Failed to get proxy auth headers: {e}")
num_retries = kwargs.get(
"num_retries", None
) ## alt. param for 'max_retries'. Use this to pass retries w/ instructor.
@@ -1536,6 +1529,8 @@ def completion( # type: ignore # noqa: PLR0915
max_retries=max_retries,
timeout=timeout,
litellm_request_debug=kwargs.get("litellm_request_debug", False),
+ tpm=kwargs.get("tpm"),
+ rpm=kwargs.get("rpm"),
)
cast(LiteLLMLoggingObj, logging).update_environment_variables(
model=model,
@@ -1563,7 +1558,7 @@ def completion( # type: ignore # noqa: PLR0915
## RESPONSES API BRIDGE LOGIC ## - check if model has 'mode: responses' in litellm.model_cost map
model_info, model = responses_api_bridge_check(
- model=model, custom_llm_provider=custom_llm_provider
+ model=model, custom_llm_provider=custom_llm_provider, web_search_options=web_search_options
)
if model_info.get("mode") == "responses":
@@ -2211,6 +2206,48 @@ def completion( # type: ignore # noqa: PLR0915
logging_obj=logging, # model call logging done inside the class as we make need to modify I/O to fit aleph alpha's requirements
client=client,
)
+ elif custom_llm_provider == "a2a":
+ # A2A (Agent-to-Agent) Protocol
+ # Resolve agent configuration from registry if model format is "a2a/"
+ api_base, api_key, headers = litellm.A2AConfig.resolve_agent_config_from_registry(
+ model=model,
+ api_base=api_base,
+ api_key=api_key,
+ headers=headers,
+ optional_params=optional_params,
+ )
+
+ # Fall back to environment variables and defaults
+ api_base = api_base or litellm.api_base or get_secret_str("A2A_API_BASE")
+
+ if api_base is None:
+ raise Exception(
+ "api_base is required for A2A provider. "
+ "Either provide api_base parameter, set A2A_API_BASE environment variable, "
+ "or register the agent in the proxy with model='a2a/'."
+ )
+
+ headers = headers or litellm.headers
+
+ response = base_llm_http_handler.completion(
+ model=model,
+ stream=stream,
+ messages=messages,
+ acompletion=acompletion,
+ api_base=api_base,
+ model_response=model_response,
+ optional_params=optional_params,
+ litellm_params=litellm_params,
+ shared_session=shared_session,
+ custom_llm_provider=custom_llm_provider,
+ timeout=timeout,
+ headers=headers,
+ encoding=_get_encoding(),
+ api_key=api_key,
+ logging_obj=logging,
+ client=client,
+ provider_config=provider_config,
+ )
elif custom_llm_provider == "gigachat":
# GigaChat - Sber AI's LLM (Russia)
api_key = (
@@ -2361,11 +2398,7 @@ def completion( # type: ignore # noqa: PLR0915
input=messages, api_key=api_key, original_response=response
)
elif custom_llm_provider == "minimax":
- api_key = (
- api_key
- or get_secret_str("MINIMAX_API_KEY")
- or litellm.api_key
- )
+ api_key = api_key or get_secret_str("MINIMAX_API_KEY") or litellm.api_key
api_base = (
api_base
@@ -2374,6 +2407,33 @@ def completion( # type: ignore # noqa: PLR0915
or "https://api.minimax.io/v1"
)
+ response = base_llm_http_handler.completion(
+ model=model,
+ messages=messages,
+ api_base=api_base,
+ custom_llm_provider=custom_llm_provider,
+ model_response=model_response,
+ encoding=_get_encoding(),
+ logging_obj=logging,
+ optional_params=optional_params,
+ timeout=timeout,
+ litellm_params=litellm_params,
+ shared_session=shared_session,
+ acompletion=acompletion,
+ stream=stream,
+ api_key=api_key,
+ headers=headers,
+ client=client,
+ provider_config=provider_config,
+ )
+ logging.post_call(
+ input=messages, api_key=api_key, original_response=response
+ )
+ elif custom_llm_provider == "hosted_vllm":
+ api_base = (
+ api_base or litellm.api_base or get_secret_str("HOSTED_VLLM_API_BASE")
+ )
+
response = base_llm_http_handler.completion(
model=model,
messages=messages,
@@ -2413,7 +2473,9 @@ def completion( # type: ignore # noqa: PLR0915
or custom_llm_provider == "wandb"
or custom_llm_provider == "clarifai"
or custom_llm_provider in litellm.openai_compatible_providers
- or JSONProviderRegistry.exists(custom_llm_provider) # JSON-configured providers
+ or JSONProviderRegistry.exists(
+ custom_llm_provider
+ ) # JSON-configured providers
or "ft:gpt-3.5-turbo" in model # finetune gpt-3.5-turbo
): # allow user to make an openai call with a custom base
# note: if a user sets a custom base - we should ensure this works
@@ -2442,6 +2504,20 @@ def completion( # type: ignore # noqa: PLR0915
headers = headers or litellm.headers
+ # Add GitHub Copilot headers (same as /responses endpoint does)
+ if custom_llm_provider == "github_copilot":
+ from litellm.llms.github_copilot.common_utils import (
+ get_copilot_default_headers,
+ )
+ from litellm.llms.github_copilot.authenticator import Authenticator
+
+ copilot_auth = Authenticator()
+ copilot_api_key = copilot_auth.get_api_key()
+ copilot_headers = get_copilot_default_headers(copilot_api_key)
+ if extra_headers:
+ copilot_headers.update(extra_headers)
+ extra_headers = copilot_headers
+
if extra_headers is not None:
optional_params["extra_headers"] = extra_headers
@@ -3100,8 +3176,8 @@ def completion( # type: ignore # noqa: PLR0915
api_key
or litellm.api_key
or litellm.openrouter_key
- or get_secret("OPENROUTER_API_KEY")
- or get_secret("OR_API_KEY")
+ or get_secret_str("OPENROUTER_API_KEY")
+ or get_secret_str("OR_API_KEY")
)
openrouter_site_url = get_secret("OR_SITE_URL") or "https://litellm.ai"
@@ -3610,9 +3686,9 @@ def completion( # type: ignore # noqa: PLR0915
"aws_region_name" not in optional_params
or optional_params["aws_region_name"] is None
):
- optional_params[
- "aws_region_name"
- ] = aws_bedrock_client.meta.region_name
+ optional_params["aws_region_name"] = (
+ aws_bedrock_client.meta.region_name
+ )
bedrock_route = BedrockModelInfo.get_bedrock_route(model)
if bedrock_route == "converse":
@@ -4542,6 +4618,13 @@ def embedding( # noqa: PLR0915
headers = {}
if extra_headers is not None:
headers.update(extra_headers)
+ # Inject proxy auth headers if configured
+ if litellm.proxy_auth is not None:
+ try:
+ proxy_headers = litellm.proxy_auth.get_auth_headers()
+ headers.update(proxy_headers)
+ except Exception as e:
+ verbose_logger.warning(f"Failed to get proxy auth headers: {e}")
### CUSTOM MODEL COST ###
input_cost_per_token = kwargs.get("input_cost_per_token", None)
output_cost_per_token = kwargs.get("output_cost_per_token", None)
@@ -4696,11 +4779,11 @@ def embedding( # noqa: PLR0915
litellm_params=litellm_params_dict,
)
elif (
- model in litellm.open_ai_embedding_models
- or custom_llm_provider == "openai"
+ custom_llm_provider == "openai"
or custom_llm_provider == "together_ai"
or custom_llm_provider == "nvidia_nim"
or custom_llm_provider == "litellm_proxy"
+ or (model in litellm.open_ai_embedding_models and custom_llm_provider is None)
):
api_base = (
api_base
@@ -4724,7 +4807,7 @@ def embedding( # noqa: PLR0915
if headers is not None and headers != {}:
optional_params["extra_headers"] = headers
-
+
if encoding_format is not None:
optional_params["encoding_format"] = encoding_format
else:
@@ -4772,9 +4855,32 @@ def embedding( # noqa: PLR0915
client=client,
aembedding=aembedding,
)
+ elif custom_llm_provider == "hosted_vllm":
+ api_base = (
+ api_base or litellm.api_base or get_secret_str("HOSTED_VLLM_API_BASE")
+ )
+
+ # set API KEY
+ if api_key is None:
+ api_key = litellm.api_key or get_secret_str("HOSTED_VLLM_API_KEY")
+
+ response = base_llm_http_handler.embedding(
+ model=model,
+ input=input,
+ custom_llm_provider=custom_llm_provider,
+ api_base=api_base,
+ api_key=api_key,
+ logging_obj=logging,
+ timeout=timeout,
+ model_response=EmbeddingResponse(),
+ optional_params=optional_params,
+ client=client,
+ aembedding=aembedding,
+ litellm_params=litellm_params_dict,
+ headers=headers or {},
+ )
elif (
custom_llm_provider == "openai_like"
- or custom_llm_provider == "hosted_vllm"
or custom_llm_provider == "llamafile"
or custom_llm_provider == "lm_studio"
):
@@ -4848,8 +4954,8 @@ def embedding( # noqa: PLR0915
api_key
or litellm.api_key
or litellm.openrouter_key
- or get_secret("OPENROUTER_API_KEY")
- or get_secret("OR_API_KEY")
+ or get_secret_str("OPENROUTER_API_KEY")
+ or get_secret_str("OR_API_KEY")
)
openrouter_site_url = get_secret("OR_SITE_URL") or "https://litellm.ai"
@@ -4866,6 +4972,36 @@ def embedding( # noqa: PLR0915
headers = openrouter_headers
+ response = base_llm_http_handler.embedding(
+ model=model,
+ input=input,
+ custom_llm_provider=custom_llm_provider,
+ api_base=api_base,
+ api_key=api_key,
+ logging_obj=logging,
+ timeout=timeout,
+ model_response=EmbeddingResponse(),
+ optional_params=optional_params,
+ client=client,
+ aembedding=aembedding,
+ litellm_params=litellm_params_dict,
+ headers=headers,
+ )
+ elif custom_llm_provider == "vercel_ai_gateway":
+ api_base = (
+ api_base
+ or litellm.api_base
+ or get_secret_str("VERCEL_AI_GATEWAY_API_BASE")
+ or "https://ai-gateway.vercel.sh/v1"
+ )
+
+ api_key = (
+ api_key
+ or litellm.api_key
+ or get_secret_str("VERCEL_AI_GATEWAY_API_KEY")
+ or get_secret_str("VERCEL_OIDC_TOKEN")
+ )
+
response = base_llm_http_handler.embedding(
model=model,
input=input,
@@ -5917,9 +6053,9 @@ def adapter_completion(
new_kwargs = translation_obj.translate_completion_input_params(kwargs=kwargs)
response: Union[ModelResponse, CustomStreamWrapper] = completion(**new_kwargs) # type: ignore
- translated_response: Optional[
- Union[BaseModel, AdapterCompletionStreamWrapper]
- ] = None
+ translated_response: Optional[Union[BaseModel, AdapterCompletionStreamWrapper]] = (
+ None
+ )
if isinstance(response, ModelResponse):
translated_response = translation_obj.translate_completion_output_params(
response=response
@@ -6624,9 +6760,9 @@ def speech( # noqa: PLR0915
ElevenLabsTextToSpeechConfig.ELEVENLABS_QUERY_PARAMS_KEY
] = query_params
- litellm_params_dict[
- ElevenLabsTextToSpeechConfig.ELEVENLABS_VOICE_ID_KEY
- ] = voice_id
+ litellm_params_dict[ElevenLabsTextToSpeechConfig.ELEVENLABS_VOICE_ID_KEY] = (
+ voice_id
+ )
if api_base is not None:
litellm_params_dict["api_base"] = api_base
@@ -6759,9 +6895,7 @@ def speech( # noqa: PLR0915
if text_to_speech_provider_config is None:
text_to_speech_provider_config = MinimaxTextToSpeechConfig()
- minimax_config = cast(
- MinimaxTextToSpeechConfig, text_to_speech_provider_config
- )
+ minimax_config = cast(MinimaxTextToSpeechConfig, text_to_speech_provider_config)
if api_base is not None:
litellm_params_dict["api_base"] = api_base
@@ -6901,7 +7035,7 @@ async def ahealth_check(
custom_llm_provider_from_params = model_params.get("custom_llm_provider", None)
api_base_from_params = model_params.get("api_base", None)
api_key_from_params = model_params.get("api_key", None)
-
+
model, custom_llm_provider, _, _ = get_llm_provider(
model=model,
custom_llm_provider=custom_llm_provider_from_params,
@@ -7134,9 +7268,9 @@ def stream_chunk_builder( # noqa: PLR0915
]
if len(content_chunks) > 0:
- response["choices"][0]["message"][
- "content"
- ] = processor.get_combined_content(content_chunks)
+ response["choices"][0]["message"]["content"] = (
+ processor.get_combined_content(content_chunks)
+ )
thinking_blocks = [
chunk
@@ -7147,9 +7281,9 @@ def stream_chunk_builder( # noqa: PLR0915
]
if len(thinking_blocks) > 0:
- response["choices"][0]["message"][
- "thinking_blocks"
- ] = processor.get_combined_thinking_content(thinking_blocks)
+ response["choices"][0]["message"]["thinking_blocks"] = (
+ processor.get_combined_thinking_content(thinking_blocks)
+ )
reasoning_chunks = [
chunk
@@ -7160,9 +7294,9 @@ def stream_chunk_builder( # noqa: PLR0915
]
if len(reasoning_chunks) > 0:
- response["choices"][0]["message"][
- "reasoning_content"
- ] = processor.get_combined_reasoning_content(reasoning_chunks)
+ response["choices"][0]["message"]["reasoning_content"] = (
+ processor.get_combined_reasoning_content(reasoning_chunks)
+ )
annotation_chunks = [
chunk
@@ -7188,6 +7322,23 @@ def stream_chunk_builder( # noqa: PLR0915
_choice = cast(Choices, response.choices[0])
_choice.message.audio = processor.get_combined_audio_content(audio_chunks)
+ # Handle image chunks from models like gemini-2.5-flash-image
+ # See: https://github.com/BerriAI/litellm/issues/19478
+ image_chunks = [
+ chunk
+ for chunk in chunks
+ if len(chunk["choices"]) > 0
+ and "images" in chunk["choices"][0]["delta"]
+ and chunk["choices"][0]["delta"]["images"] is not None
+ ]
+
+ if len(image_chunks) > 0:
+ # Images come complete in a single chunk, collect all images from all chunks
+ all_images = []
+ for chunk in image_chunks:
+ all_images.extend(chunk["choices"][0]["delta"]["images"])
+ response["choices"][0]["message"]["images"] = all_images
+
# Combine provider_specific_fields from streaming chunks (e.g., web_search_results, citations)
# See: https://github.com/BerriAI/litellm/issues/17737
provider_specific_chunks = [
@@ -7271,12 +7422,16 @@ def _get_encoding():
def __getattr__(name: str) -> Any:
"""Lazy import handler for main module"""
if name == "encoding":
- # Lazy load encoding to avoid heavy tiktoken import at module load time
- _encoding = tiktoken.get_encoding("cl100k_base")
+ # Use _get_default_encoding which properly sets TIKTOKEN_CACHE_DIR
+ # before loading tiktoken, ensuring the local cache is used
+ # instead of downloading from the internet
+ from litellm._lazy_imports import _get_default_encoding
+ _encoding = _get_default_encoding()
# Cache it in the module's __dict__ for subsequent accesses
import sys
+
sys.modules[__name__].__dict__["encoding"] = _encoding
global _encoding_cache
_encoding_cache = _encoding
return _encoding
- raise AttributeError(f"module {__name__!r} has no attribute {name!r}")
\ No newline at end of file
+ raise AttributeError(f"module {__name__!r} has no attribute {name!r}")
diff --git a/litellm/model_prices_and_context_window_backup.json b/litellm/model_prices_and_context_window_backup.json
index ab034d9f51b..4704549e716 100644
--- a/litellm/model_prices_and_context_window_backup.json
+++ b/litellm/model_prices_and_context_window_backup.json
@@ -354,6 +354,25 @@
"supports_video_input": true,
"supports_vision": true
},
+ "amazon.nova-2-pro-preview-20251202-v1:0": {
+ "cache_read_input_token_cost": 5.46875e-07,
+ "input_cost_per_token": 2.1875e-06,
+ "input_cost_per_image_token": 2.1875e-06,
+ "input_cost_per_audio_token": 2.1875e-06,
+ "litellm_provider": "bedrock_converse",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 64000,
+ "max_tokens": 64000,
+ "mode": "chat",
+ "output_cost_per_token": 1.75e-05,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_video_input": true,
+ "supports_vision": true
+ },
"apac.amazon.nova-2-lite-v1:0": {
"cache_read_input_token_cost": 8.25e-08,
"input_cost_per_token": 3.3e-07,
@@ -371,6 +390,25 @@
"supports_video_input": true,
"supports_vision": true
},
+ "apac.amazon.nova-2-pro-preview-20251202-v1:0": {
+ "cache_read_input_token_cost": 5.46875e-07,
+ "input_cost_per_token": 2.1875e-06,
+ "input_cost_per_image_token": 2.1875e-06,
+ "input_cost_per_audio_token": 2.1875e-06,
+ "litellm_provider": "bedrock_converse",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 64000,
+ "max_tokens": 64000,
+ "mode": "chat",
+ "output_cost_per_token": 1.75e-05,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_video_input": true,
+ "supports_vision": true
+ },
"eu.amazon.nova-2-lite-v1:0": {
"cache_read_input_token_cost": 8.25e-08,
"input_cost_per_token": 3.3e-07,
@@ -388,6 +426,25 @@
"supports_video_input": true,
"supports_vision": true
},
+ "eu.amazon.nova-2-pro-preview-20251202-v1:0": {
+ "cache_read_input_token_cost": 5.46875e-07,
+ "input_cost_per_token": 2.1875e-06,
+ "input_cost_per_image_token": 2.1875e-06,
+ "input_cost_per_audio_token": 2.1875e-06,
+ "litellm_provider": "bedrock_converse",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 64000,
+ "max_tokens": 64000,
+ "mode": "chat",
+ "output_cost_per_token": 1.75e-05,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_video_input": true,
+ "supports_vision": true
+ },
"us.amazon.nova-2-lite-v1:0": {
"cache_read_input_token_cost": 8.25e-08,
"input_cost_per_token": 3.3e-07,
@@ -405,6 +462,25 @@
"supports_video_input": true,
"supports_vision": true
},
+ "us.amazon.nova-2-pro-preview-20251202-v1:0": {
+ "cache_read_input_token_cost": 5.46875e-07,
+ "input_cost_per_token": 2.1875e-06,
+ "input_cost_per_image_token": 2.1875e-06,
+ "input_cost_per_audio_token": 2.1875e-06,
+ "litellm_provider": "bedrock_converse",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 64000,
+ "max_tokens": 64000,
+ "mode": "chat",
+ "output_cost_per_token": 1.75e-05,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_video_input": true,
+ "supports_vision": true
+ },
"amazon.nova-2-multimodal-embeddings-v1:0": {
"litellm_provider": "bedrock",
"max_input_tokens": 8172,
@@ -668,12 +744,13 @@
"supports_response_schema": true,
"supports_tool_choice": true,
"supports_vision": true,
- "tool_use_system_prompt_tokens": 346
+ "tool_use_system_prompt_tokens": 346,
+ "supports_native_streaming": true
},
"anthropic.claude-3-5-sonnet-20240620-v1:0": {
"input_cost_per_token": 3e-06,
"litellm_provider": "bedrock",
- "max_input_tokens": 200000,
+ "max_input_tokens": 1000000,
"max_output_tokens": 4096,
"max_tokens": 4096,
"mode": "chat",
@@ -682,14 +759,22 @@
"supports_pdf_input": true,
"supports_response_schema": true,
"supports_tool_choice": true,
- "supports_vision": true
+ "supports_vision": true,
+ "input_cost_per_token_above_200k_tokens": 6e-06,
+ "output_cost_per_token_above_200k_tokens": 3e-05,
+ "cache_creation_input_token_cost_above_200k_tokens": 7.5e-06,
+ "cache_read_input_token_cost_above_200k_tokens": 6e-07,
+ "cache_creation_input_token_cost_above_1hr": 7.5e-06,
+ "cache_creation_input_token_cost_above_1hr_above_200k_tokens": 1.5e-05,
+ "cache_creation_input_token_cost": 3.75e-06,
+ "cache_read_input_token_cost": 3e-07
},
"anthropic.claude-3-5-sonnet-20241022-v2:0": {
"cache_creation_input_token_cost": 3.75e-06,
"cache_read_input_token_cost": 3e-07,
"input_cost_per_token": 3e-06,
"litellm_provider": "bedrock",
- "max_input_tokens": 200000,
+ "max_input_tokens": 1000000,
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
@@ -701,7 +786,13 @@
"supports_prompt_caching": true,
"supports_response_schema": true,
"supports_tool_choice": true,
- "supports_vision": true
+ "supports_vision": true,
+ "input_cost_per_token_above_200k_tokens": 6e-06,
+ "output_cost_per_token_above_200k_tokens": 3e-05,
+ "cache_creation_input_token_cost_above_200k_tokens": 7.5e-06,
+ "cache_read_input_token_cost_above_200k_tokens": 6e-07,
+ "cache_creation_input_token_cost_above_1hr": 7.5e-06,
+ "cache_creation_input_token_cost_above_1hr_above_200k_tokens": 1.5e-05
},
"anthropic.claude-3-7-sonnet-20240620-v1:0": {
"cache_creation_input_token_cost": 4.5e-06,
@@ -872,6 +963,336 @@
"supports_vision": true,
"tool_use_system_prompt_tokens": 159
},
+ "anthropic.claude-opus-4-6-v1": {
+ "cache_creation_input_token_cost": 6.25e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.25e-05,
+ "cache_read_input_token_cost": 5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1e-06,
+ "input_cost_per_token": 5e-06,
+ "input_cost_per_token_above_200k_tokens": 1e-05,
+ "litellm_provider": "bedrock_converse",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.5e-05,
+ "output_cost_per_token_above_200k_tokens": 3.75e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
+ },
+ "anthropic.claude-opus-4-6-v1": {
+ "cache_creation_input_token_cost": 6.25e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.25e-05,
+ "cache_read_input_token_cost": 5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1e-06,
+ "input_cost_per_token": 5e-06,
+ "input_cost_per_token_above_200k_tokens": 1e-05,
+ "litellm_provider": "bedrock_converse",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.5e-05,
+ "output_cost_per_token_above_200k_tokens": 3.75e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
+ },
+ "global.anthropic.claude-opus-4-6-v1": {
+ "cache_creation_input_token_cost": 6.25e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.25e-05,
+ "cache_read_input_token_cost": 5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1e-06,
+ "input_cost_per_token": 5e-06,
+ "input_cost_per_token_above_200k_tokens": 1e-05,
+ "litellm_provider": "bedrock_converse",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.5e-05,
+ "output_cost_per_token_above_200k_tokens": 3.75e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
+ },
+ "global.anthropic.claude-opus-4-6-v1": {
+ "cache_creation_input_token_cost": 6.25e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.25e-05,
+ "cache_read_input_token_cost": 5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1e-06,
+ "input_cost_per_token": 5e-06,
+ "input_cost_per_token_above_200k_tokens": 1e-05,
+ "litellm_provider": "bedrock_converse",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.5e-05,
+ "output_cost_per_token_above_200k_tokens": 3.75e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
+ },
+ "us.anthropic.claude-opus-4-6-v1:0": {
+ "cache_creation_input_token_cost": 6.875e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.375e-05,
+ "cache_read_input_token_cost": 5.5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1.1e-06,
+ "input_cost_per_token": 5.5e-06,
+ "input_cost_per_token_above_200k_tokens": 1.1e-05,
+ "litellm_provider": "bedrock_converse",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.75e-05,
+ "output_cost_per_token_above_200k_tokens": 4.125e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
+ },
+ "us.anthropic.claude-opus-4-6-v1": {
+ "cache_creation_input_token_cost": 6.875e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.375e-05,
+ "cache_read_input_token_cost": 5.5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1.1e-06,
+ "input_cost_per_token": 5.5e-06,
+ "input_cost_per_token_above_200k_tokens": 1.1e-05,
+ "litellm_provider": "bedrock_converse",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.75e-05,
+ "output_cost_per_token_above_200k_tokens": 4.125e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
+ },
+ "eu.anthropic.claude-opus-4-6-v1": {
+ "cache_creation_input_token_cost": 6.875e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.375e-05,
+ "cache_read_input_token_cost": 5.5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1.1e-06,
+ "input_cost_per_token": 5.5e-06,
+ "input_cost_per_token_above_200k_tokens": 1.1e-05,
+ "litellm_provider": "bedrock_converse",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.75e-05,
+ "output_cost_per_token_above_200k_tokens": 4.125e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
+ },
+ "eu.anthropic.claude-opus-4-6-v1": {
+ "cache_creation_input_token_cost": 6.875e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.375e-05,
+ "cache_read_input_token_cost": 5.5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1.1e-06,
+ "input_cost_per_token": 5.5e-06,
+ "input_cost_per_token_above_200k_tokens": 1.1e-05,
+ "litellm_provider": "bedrock_converse",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.75e-05,
+ "output_cost_per_token_above_200k_tokens": 4.125e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
+ },
+ "apac.anthropic.claude-opus-4-6-v1": {
+ "cache_creation_input_token_cost": 6.875e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.375e-05,
+ "cache_read_input_token_cost": 5.5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1.1e-06,
+ "input_cost_per_token": 5.5e-06,
+ "input_cost_per_token_above_200k_tokens": 1.1e-05,
+ "litellm_provider": "bedrock_converse",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.75e-05,
+ "output_cost_per_token_above_200k_tokens": 4.125e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
+ },
+ "apac.anthropic.claude-opus-4-6-v1": {
+ "cache_creation_input_token_cost": 6.875e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.375e-05,
+ "cache_read_input_token_cost": 5.5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1.1e-06,
+ "input_cost_per_token": 5.5e-06,
+ "input_cost_per_token_above_200k_tokens": 1.1e-05,
+ "litellm_provider": "bedrock_converse",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.75e-05,
+ "output_cost_per_token_above_200k_tokens": 4.125e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
+ },
+ "au.anthropic.claude-opus-4-6-v1:0": {
+ "cache_creation_input_token_cost": 6.875e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.375e-05,
+ "cache_read_input_token_cost": 5.5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1.1e-06,
+ "input_cost_per_token": 5.5e-06,
+ "input_cost_per_token_above_200k_tokens": 1.1e-05,
+ "litellm_provider": "bedrock_converse",
+ "max_input_tokens": 200000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.75e-05,
+ "output_cost_per_token_above_200k_tokens": 4.125e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
+ },
"anthropic.claude-sonnet-4-20250514-v1:0": {
"cache_creation_input_token_cost": 3.75e-06,
"cache_read_input_token_cost": 3e-07,
@@ -1312,6 +1733,9 @@
"supports_function_calling": true
},
"azure_ai/claude-haiku-4-5": {
+ "cache_creation_input_token_cost": 1.25e-06,
+ "cache_creation_input_token_cost_above_1hr": 2e-06,
+ "cache_read_input_token_cost": 1e-07,
"input_cost_per_token": 1e-06,
"litellm_provider": "azure_ai",
"max_input_tokens": 200000,
@@ -1330,6 +1754,9 @@
"supports_vision": true
},
"azure_ai/claude-opus-4-5": {
+ "cache_creation_input_token_cost": 6.25e-06,
+ "cache_creation_input_token_cost_above_1hr": 1e-05,
+ "cache_read_input_token_cost": 5e-07,
"input_cost_per_token": 5e-06,
"litellm_provider": "azure_ai",
"max_input_tokens": 200000,
@@ -1347,7 +1774,37 @@
"supports_tool_choice": true,
"supports_vision": true
},
+ "azure_ai/claude-opus-4-6": {
+ "input_cost_per_token": 5e-06,
+ "output_cost_per_token": 2.5e-05,
+ "litellm_provider": "azure_ai",
+ "max_input_tokens": 200000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "cache_creation_input_token_cost": 6.25e-06,
+ "cache_creation_input_token_cost_above_1hr": 1e-05,
+ "cache_read_input_token_cost": 5e-07,
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 159
+ },
"azure_ai/claude-opus-4-1": {
+ "cache_creation_input_token_cost": 1.875e-05,
+ "cache_creation_input_token_cost_above_1hr": 3e-05,
+ "cache_read_input_token_cost": 1.5e-06,
"input_cost_per_token": 1.5e-05,
"litellm_provider": "azure_ai",
"max_input_tokens": 200000,
@@ -1366,6 +1823,9 @@
"supports_vision": true
},
"azure_ai/claude-sonnet-4-5": {
+ "cache_creation_input_token_cost": 3.75e-06,
+ "cache_creation_input_token_cost_above_1hr": 6e-06,
+ "cache_read_input_token_cost": 3e-07,
"input_cost_per_token": 3e-06,
"litellm_provider": "azure_ai",
"max_input_tokens": 200000,
@@ -1429,6 +1889,14 @@
"supports_response_schema": true,
"supports_tool_choice": true
},
+ "azure_ai/model_router": {
+ "input_cost_per_token": 1.4e-07,
+ "output_cost_per_token": 0,
+ "litellm_provider": "azure_ai",
+ "mode": "chat",
+ "source": "https://azure.microsoft.com/en-us/pricing/details/ai-services/",
+ "comment": "Flat cost of $0.14 per M input tokens for Azure AI Foundry Model Router infrastructure. Use pattern: azure_ai/model_router/ where deployment-name is your Azure deployment (e.g., azure-model-router)"
+ },
"azure/eu/gpt-4o-2024-08-06": {
"deprecation_date": "2026-02-27",
"cache_read_input_token_cost": 1.375e-06,
@@ -3118,7 +3586,7 @@
"supports_reasoning": true,
"supports_response_schema": true,
"supports_system_messages": true,
- "supports_tool_choice": false,
+ "supports_tool_choice": true,
"supports_vision": true
},
"azure/gpt-5-chat-latest": {
@@ -3150,7 +3618,7 @@
"supports_reasoning": true,
"supports_response_schema": true,
"supports_system_messages": true,
- "supports_tool_choice": false,
+ "supports_tool_choice": true,
"supports_vision": true
},
"azure/gpt-5-codex": {
@@ -3638,13 +4106,12 @@
"cache_read_input_token_cost": 1.75e-07,
"input_cost_per_token": 1.75e-06,
"litellm_provider": "azure",
- "max_input_tokens": 128000,
- "max_output_tokens": 16384,
- "max_tokens": 16384,
- "mode": "chat",
+ "max_input_tokens": 272000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "responses",
"output_cost_per_token": 1.4e-05,
"supported_endpoints": [
- "/v1/chat/completions",
"/v1/responses"
],
"supported_modalities": [
@@ -6620,13 +7087,13 @@
"supports_tool_choice": true
},
"cerebras/gpt-oss-120b": {
- "input_cost_per_token": 2.5e-07,
+ "input_cost_per_token": 3.5e-07,
"litellm_provider": "cerebras",
"max_input_tokens": 131072,
"max_output_tokens": 32768,
"max_tokens": 32768,
"mode": "chat",
- "output_cost_per_token": 6.9e-07,
+ "output_cost_per_token": 7.5e-07,
"source": "https://www.cerebras.ai/blog/openai-gpt-oss-120b-runs-fastest-on-cerebras",
"supports_function_calling": true,
"supports_parallel_function_calling": true,
@@ -6644,6 +7111,7 @@
"output_cost_per_token": 8e-07,
"source": "https://inference-docs.cerebras.ai/support/pricing",
"supports_function_calling": true,
+ "supports_reasoning": true,
"supports_tool_choice": true
},
"cerebras/zai-glm-4.6": {
@@ -7344,6 +7812,130 @@
"supports_vision": true,
"tool_use_system_prompt_tokens": 159
},
+ "claude-opus-4-6": {
+ "cache_creation_input_token_cost": 6.25e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.25e-05,
+ "cache_creation_input_token_cost_above_1hr": 1e-05,
+ "cache_read_input_token_cost": 5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1e-06,
+ "input_cost_per_token": 5e-06,
+ "input_cost_per_token_above_200k_tokens": 1e-05,
+ "litellm_provider": "anthropic",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.5e-05,
+ "output_cost_per_token_above_200k_tokens": 3.75e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
+ },
+ "us/claude-opus-4-6": {
+ "cache_creation_input_token_cost": 6.875e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.375e-05,
+ "cache_creation_input_token_cost_above_1hr": 1.1e-05,
+ "cache_read_input_token_cost": 5.5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1.1e-06,
+ "input_cost_per_token": 5.5e-06,
+ "input_cost_per_token_above_200k_tokens": 1.1e-05,
+ "litellm_provider": "anthropic",
+ "max_input_tokens": 200000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.75e-05,
+ "output_cost_per_token_above_200k_tokens": 4.125e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
+ },
+ "claude-opus-4-6-20260205": {
+ "cache_creation_input_token_cost": 6.25e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.25e-05,
+ "cache_creation_input_token_cost_above_1hr": 1e-05,
+ "cache_read_input_token_cost": 5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1e-06,
+ "input_cost_per_token": 5e-06,
+ "input_cost_per_token_above_200k_tokens": 1e-05,
+ "litellm_provider": "anthropic",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.5e-05,
+ "output_cost_per_token_above_200k_tokens": 3.75e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
+ },
+ "us/claude-opus-4-6-20260205": {
+ "cache_creation_input_token_cost": 6.875e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.375e-05,
+ "cache_creation_input_token_cost_above_1hr": 1.1e-05,
+ "cache_read_input_token_cost": 5.5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1.1e-06,
+ "input_cost_per_token": 5.5e-06,
+ "input_cost_per_token_above_200k_tokens": 1.1e-05,
+ "litellm_provider": "anthropic",
+ "max_input_tokens": 200000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.75e-05,
+ "output_cost_per_token_above_200k_tokens": 4.125e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
+ },
"claude-sonnet-4-20250514": {
"deprecation_date": "2026-05-14",
"cache_creation_input_token_cost": 3.75e-06,
@@ -9776,6 +10368,7 @@
"supports_tool_choice": true
},
"deepinfra/google/gemini-2.0-flash-001": {
+ "deprecation_date": "2026-03-31",
"max_tokens": 1000000,
"max_input_tokens": 1000000,
"max_output_tokens": 1000000,
@@ -10219,6 +10812,48 @@
"mode": "completion",
"output_cost_per_token": 5e-07
},
+ "deepseek-v3-2-251201": {
+ "input_cost_per_token": 0.0,
+ "litellm_provider": "volcengine",
+ "max_input_tokens": 98304,
+ "max_output_tokens": 32768,
+ "max_tokens": 32768,
+ "mode": "chat",
+ "output_cost_per_token": 0.0,
+ "supports_assistant_prefill": true,
+ "supports_function_calling": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_tool_choice": true
+ },
+ "glm-4-7-251222": {
+ "input_cost_per_token": 0.0,
+ "litellm_provider": "volcengine",
+ "max_input_tokens": 204800,
+ "max_output_tokens": 131072,
+ "max_tokens": 131072,
+ "mode": "chat",
+ "output_cost_per_token": 0.0,
+ "supports_assistant_prefill": true,
+ "supports_function_calling": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_tool_choice": true
+ },
+ "kimi-k2-thinking-251104": {
+ "input_cost_per_token": 0.0,
+ "litellm_provider": "volcengine",
+ "max_input_tokens": 229376,
+ "max_output_tokens": 32768,
+ "max_tokens": 32768,
+ "mode": "chat",
+ "output_cost_per_token": 0.0,
+ "supports_assistant_prefill": true,
+ "supports_function_calling": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_tool_choice": true
+ },
"doubao-embedding": {
"input_cost_per_token": 0.0,
"litellm_provider": "volcengine",
@@ -10421,6 +11056,32 @@
"/v1/audio/transcriptions"
]
},
+ "elevenlabs/eleven_v3": {
+ "input_cost_per_character": 0.00018,
+ "litellm_provider": "elevenlabs",
+ "metadata": {
+ "calculation": "$0.18/1000 characters (Scale plan pricing, 1 credit per character)",
+ "notes": "ElevenLabs Eleven v3 - most expressive TTS model with 70+ languages and audio tags support"
+ },
+ "mode": "audio_speech",
+ "source": "https://elevenlabs.io/pricing",
+ "supported_endpoints": [
+ "/v1/audio/speech"
+ ]
+ },
+ "elevenlabs/eleven_multilingual_v2": {
+ "input_cost_per_character": 0.00018,
+ "litellm_provider": "elevenlabs",
+ "metadata": {
+ "calculation": "$0.18/1000 characters (Scale plan pricing, 1 credit per character)",
+ "notes": "ElevenLabs Eleven Multilingual v2 - default TTS model with 29 languages support"
+ },
+ "mode": "audio_speech",
+ "source": "https://elevenlabs.io/pricing",
+ "supported_endpoints": [
+ "/v1/audio/speech"
+ ]
+ },
"embed-english-light-v2.0": {
"input_cost_per_token": 1e-07,
"litellm_provider": "cohere",
@@ -12093,6 +12754,7 @@
},
"gemini-2.0-flash": {
"cache_read_input_token_cost": 2.5e-08,
+ "deprecation_date": "2026-03-31",
"input_cost_per_audio_token": 7e-07,
"input_cost_per_token": 1e-07,
"litellm_provider": "vertex_ai-language-models",
@@ -12132,7 +12794,7 @@
},
"gemini-2.0-flash-001": {
"cache_read_input_token_cost": 3.75e-08,
- "deprecation_date": "2026-02-05",
+ "deprecation_date": "2026-03-31",
"input_cost_per_audio_token": 1e-06,
"input_cost_per_token": 1.5e-07,
"litellm_provider": "vertex_ai-language-models",
@@ -12218,6 +12880,7 @@
},
"gemini-2.0-flash-lite": {
"cache_read_input_token_cost": 1.875e-08,
+ "deprecation_date": "2026-03-31",
"input_cost_per_audio_token": 7.5e-08,
"input_cost_per_token": 7.5e-08,
"litellm_provider": "vertex_ai-language-models",
@@ -12253,7 +12916,7 @@
},
"gemini-2.0-flash-lite-001": {
"cache_read_input_token_cost": 1.875e-08,
- "deprecation_date": "2026-02-25",
+ "deprecation_date": "2026-03-31",
"input_cost_per_audio_token": 7.5e-08,
"input_cost_per_token": 7.5e-08,
"litellm_provider": "vertex_ai-language-models",
@@ -12695,6 +13358,40 @@
"supports_vision": true,
"supports_web_search": true
},
+ "deep-research-pro-preview-12-2025": {
+ "input_cost_per_image": 0.0011,
+ "input_cost_per_token": 2e-06,
+ "input_cost_per_token_batches": 1e-06,
+ "litellm_provider": "vertex_ai-language-models",
+ "max_input_tokens": 65536,
+ "max_output_tokens": 32768,
+ "max_tokens": 32768,
+ "mode": "image_generation",
+ "output_cost_per_image": 0.134,
+ "output_cost_per_image_token": 0.00012,
+ "output_cost_per_token": 1.2e-05,
+ "output_cost_per_token_batches": 6e-06,
+ "source": "https://ai.google.dev/gemini-api/docs/pricing",
+ "supported_endpoints": [
+ "/v1/chat/completions",
+ "/v1/completions",
+ "/v1/batch"
+ ],
+ "supported_modalities": [
+ "text",
+ "image"
+ ],
+ "supported_output_modalities": [
+ "text",
+ "image"
+ ],
+ "supports_function_calling": false,
+ "supports_prompt_caching": true,
+ "supports_response_schema": true,
+ "supports_system_messages": true,
+ "supports_vision": true,
+ "supports_web_search": true
+ },
"gemini-2.5-flash-lite": {
"cache_read_input_token_cost": 1e-08,
"input_cost_per_audio_token": 3e-07,
@@ -13149,7 +13846,8 @@
"supports_tool_choice": true,
"supports_video_input": true,
"supports_vision": true,
- "supports_web_search": true
+ "supports_web_search": true,
+ "supports_native_streaming": true
},
"vertex_ai/gemini-3-pro-preview": {
"cache_read_input_token_cost": 2e-07,
@@ -13197,7 +13895,8 @@
"supports_tool_choice": true,
"supports_video_input": true,
"supports_vision": true,
- "supports_web_search": true
+ "supports_web_search": true,
+ "supports_native_streaming": true
},
"vertex_ai/gemini-3-flash-preview": {
"cache_read_input_token_cost": 5e-08,
@@ -13240,7 +13939,8 @@
"supports_tool_choice": true,
"supports_video_input": true,
"supports_vision": true,
- "supports_web_search": true
+ "supports_web_search": true,
+ "supports_native_streaming": true
},
"gemini-2.5-pro-exp-03-25": {
"cache_read_input_token_cost": 1.25e-07,
@@ -13465,6 +14165,79 @@
"supports_vision": true,
"supports_web_search": true
},
+ "gemini-robotics-er-1.5-preview": {
+ "cache_read_input_token_cost": 0,
+ "input_cost_per_token": 3e-07,
+ "input_cost_per_audio_token": 1e-06,
+ "litellm_provider": "vertex_ai-language-models",
+ "max_input_tokens": 1048576,
+ "max_output_tokens": 65535,
+ "max_tokens": 65535,
+ "mode": "chat",
+ "output_cost_per_token": 2.5e-06,
+ "output_cost_per_reasoning_token": 2.5e-06,
+ "source": "https://ai.google.dev/gemini-api/docs/models#gemini-robotics-er-1-5-preview",
+ "supported_endpoints": [
+ "/v1/chat/completions",
+ "/v1/completions"
+ ],
+ "supported_modalities": [
+ "text",
+ "image",
+ "video",
+ "audio"
+ ],
+ "supported_output_modalities": [
+ "text"
+ ],
+ "supports_audio_output": false,
+ "supports_function_calling": true,
+ "supports_parallel_function_calling": true,
+ "supports_prompt_caching": false,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_system_messages": true,
+ "supports_tool_choice": true,
+ "supports_url_context": true,
+ "supports_vision": true
+ },
+ "gemini/gemini-robotics-er-1.5-preview": {
+ "cache_read_input_token_cost": 0,
+ "input_cost_per_token": 3e-07,
+ "input_cost_per_audio_token": 1e-06,
+ "litellm_provider": "gemini",
+ "max_input_tokens": 1048576,
+ "max_output_tokens": 65535,
+ "max_tokens": 65535,
+ "mode": "chat",
+ "output_cost_per_token": 2.5e-06,
+ "output_cost_per_reasoning_token": 2.5e-06,
+ "source": "https://ai.google.dev/gemini-api/docs/models#gemini-robotics-er-1-5-preview",
+ "supported_endpoints": [
+ "/v1/chat/completions",
+ "/v1/completions"
+ ],
+ "supported_modalities": [
+ "text",
+ "image",
+ "video",
+ "audio"
+ ],
+ "supported_output_modalities": [
+ "text"
+ ],
+ "supports_audio_output": false,
+ "supports_function_calling": true,
+ "supports_parallel_function_calling": true,
+ "supports_prompt_caching": false,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_system_messages": true,
+ "supports_tool_choice": true,
+ "supports_url_context": true,
+ "supports_vision": true,
+ "supports_web_search": true
+ },
"gemini-2.5-computer-use-preview-10-2025": {
"input_cost_per_token": 1.25e-06,
"input_cost_per_token_above_200k_tokens": 2.5e-06,
@@ -13918,6 +14691,7 @@
},
"gemini/gemini-2.0-flash": {
"cache_read_input_token_cost": 2.5e-08,
+ "deprecation_date": "2026-03-31",
"input_cost_per_audio_token": 7e-07,
"input_cost_per_token": 1e-07,
"litellm_provider": "gemini",
@@ -13958,6 +14732,7 @@
},
"gemini/gemini-2.0-flash-001": {
"cache_read_input_token_cost": 2.5e-08,
+ "deprecation_date": "2026-03-31",
"input_cost_per_audio_token": 7e-07,
"input_cost_per_token": 1e-07,
"litellm_provider": "gemini",
@@ -14045,6 +14820,7 @@
},
"gemini/gemini-2.0-flash-lite": {
"cache_read_input_token_cost": 1.875e-08,
+ "deprecation_date": "2026-03-31",
"input_cost_per_audio_token": 7.5e-08,
"input_cost_per_token": 7.5e-08,
"litellm_provider": "gemini",
@@ -14531,6 +15307,42 @@
"supports_vision": true,
"supports_web_search": true
},
+ "gemini/deep-research-pro-preview-12-2025": {
+ "input_cost_per_image": 0.0011,
+ "input_cost_per_token": 2e-06,
+ "input_cost_per_token_batches": 1e-06,
+ "litellm_provider": "gemini",
+ "max_input_tokens": 65536,
+ "max_output_tokens": 32768,
+ "max_tokens": 32768,
+ "mode": "image_generation",
+ "output_cost_per_image": 0.134,
+ "output_cost_per_image_token": 0.00012,
+ "output_cost_per_token": 1.2e-05,
+ "rpm": 1000,
+ "tpm": 4000000,
+ "output_cost_per_token_batches": 6e-06,
+ "source": "https://ai.google.dev/gemini-api/docs/pricing",
+ "supported_endpoints": [
+ "/v1/chat/completions",
+ "/v1/completions",
+ "/v1/batch"
+ ],
+ "supported_modalities": [
+ "text",
+ "image"
+ ],
+ "supported_output_modalities": [
+ "text",
+ "image"
+ ],
+ "supports_function_calling": false,
+ "supports_prompt_caching": true,
+ "supports_response_schema": true,
+ "supports_system_messages": true,
+ "supports_vision": true,
+ "supports_web_search": true
+ },
"gemini/gemini-2.5-flash-lite": {
"cache_read_input_token_cost": 1e-08,
"input_cost_per_audio_token": 3e-07,
@@ -15115,6 +15927,7 @@
"supports_url_context": true,
"supports_vision": true,
"supports_web_search": true,
+ "supports_native_streaming": true,
"tpm": 800000
},
"gemini-3-flash-preview": {
@@ -15160,7 +15973,8 @@
"supports_tool_choice": true,
"supports_url_context": true,
"supports_vision": true,
- "supports_web_search": true
+ "supports_web_search": true,
+ "supports_native_streaming": true
},
"gemini/gemini-2.5-pro-exp-03-25": {
"cache_read_input_token_cost": 0.0,
@@ -16094,6 +16908,181 @@
"output_cost_per_token": 0.0,
"output_vector_size": 2560
},
+ "gmi/anthropic/claude-opus-4.5": {
+ "input_cost_per_token": 5e-06,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 409600,
+ "max_output_tokens": 32000,
+ "max_tokens": 32000,
+ "mode": "chat",
+ "output_cost_per_token": 2.5e-05,
+ "supports_function_calling": true,
+ "supports_vision": true
+ },
+ "gmi/anthropic/claude-sonnet-4.5": {
+ "input_cost_per_token": 3e-06,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 409600,
+ "max_output_tokens": 32000,
+ "max_tokens": 32000,
+ "mode": "chat",
+ "output_cost_per_token": 1.5e-05,
+ "supports_function_calling": true,
+ "supports_vision": true
+ },
+ "gmi/anthropic/claude-sonnet-4": {
+ "input_cost_per_token": 3e-06,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 409600,
+ "max_output_tokens": 32000,
+ "max_tokens": 32000,
+ "mode": "chat",
+ "output_cost_per_token": 1.5e-05,
+ "supports_function_calling": true,
+ "supports_vision": true
+ },
+ "gmi/anthropic/claude-opus-4": {
+ "input_cost_per_token": 1.5e-05,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 409600,
+ "max_output_tokens": 32000,
+ "max_tokens": 32000,
+ "mode": "chat",
+ "output_cost_per_token": 7.5e-05,
+ "supports_function_calling": true,
+ "supports_vision": true
+ },
+ "gmi/openai/gpt-5.2": {
+ "input_cost_per_token": 1.75e-06,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 409600,
+ "max_output_tokens": 32000,
+ "max_tokens": 32000,
+ "mode": "chat",
+ "output_cost_per_token": 1.4e-05,
+ "supports_function_calling": true
+ },
+ "gmi/openai/gpt-5.1": {
+ "input_cost_per_token": 1.25e-06,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 409600,
+ "max_output_tokens": 32000,
+ "max_tokens": 32000,
+ "mode": "chat",
+ "output_cost_per_token": 1e-05,
+ "supports_function_calling": true
+ },
+ "gmi/openai/gpt-5": {
+ "input_cost_per_token": 1.25e-06,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 409600,
+ "max_output_tokens": 32000,
+ "max_tokens": 32000,
+ "mode": "chat",
+ "output_cost_per_token": 1e-05,
+ "supports_function_calling": true
+ },
+ "gmi/openai/gpt-4o": {
+ "input_cost_per_token": 2.5e-06,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 131072,
+ "max_output_tokens": 16384,
+ "max_tokens": 16384,
+ "mode": "chat",
+ "output_cost_per_token": 1e-05,
+ "supports_function_calling": true,
+ "supports_vision": true
+ },
+ "gmi/openai/gpt-4o-mini": {
+ "input_cost_per_token": 1.5e-07,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 131072,
+ "max_output_tokens": 16384,
+ "max_tokens": 16384,
+ "mode": "chat",
+ "output_cost_per_token": 6e-07,
+ "supports_function_calling": true,
+ "supports_vision": true
+ },
+ "gmi/deepseek-ai/DeepSeek-V3.2": {
+ "input_cost_per_token": 2.8e-07,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 163840,
+ "max_output_tokens": 16384,
+ "max_tokens": 16384,
+ "mode": "chat",
+ "output_cost_per_token": 4e-07,
+ "supports_function_calling": true
+ },
+ "gmi/deepseek-ai/DeepSeek-V3-0324": {
+ "input_cost_per_token": 2.8e-07,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 163840,
+ "max_output_tokens": 16384,
+ "max_tokens": 16384,
+ "mode": "chat",
+ "output_cost_per_token": 8.8e-07,
+ "supports_function_calling": true
+ },
+ "gmi/google/gemini-3-pro-preview": {
+ "input_cost_per_token": 2e-06,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 1048576,
+ "max_output_tokens": 65536,
+ "max_tokens": 65536,
+ "mode": "chat",
+ "output_cost_per_token": 1.2e-05,
+ "supports_function_calling": true,
+ "supports_vision": true
+ },
+ "gmi/google/gemini-3-flash-preview": {
+ "input_cost_per_token": 5e-07,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 1048576,
+ "max_output_tokens": 65536,
+ "max_tokens": 65536,
+ "mode": "chat",
+ "output_cost_per_token": 3e-06,
+ "supports_function_calling": true,
+ "supports_vision": true
+ },
+ "gmi/moonshotai/Kimi-K2-Thinking": {
+ "input_cost_per_token": 8e-07,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 262144,
+ "max_output_tokens": 16384,
+ "max_tokens": 16384,
+ "mode": "chat",
+ "output_cost_per_token": 1.2e-06
+ },
+ "gmi/MiniMaxAI/MiniMax-M2.1": {
+ "input_cost_per_token": 3e-07,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 196608,
+ "max_output_tokens": 16384,
+ "max_tokens": 16384,
+ "mode": "chat",
+ "output_cost_per_token": 1.2e-06
+ },
+ "gmi/Qwen/Qwen3-VL-235B-A22B-Instruct-FP8": {
+ "input_cost_per_token": 3e-07,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 262144,
+ "max_output_tokens": 16384,
+ "max_tokens": 16384,
+ "mode": "chat",
+ "output_cost_per_token": 1.4e-06,
+ "supports_vision": true
+ },
+ "gmi/zai-org/GLM-4.7-FP8": {
+ "input_cost_per_token": 4e-07,
+ "litellm_provider": "gmi",
+ "max_input_tokens": 202752,
+ "max_output_tokens": 16384,
+ "max_tokens": 16384,
+ "mode": "chat",
+ "output_cost_per_token": 2e-06
+ },
"google.gemma-3-12b-it": {
"input_cost_per_token": 9e-08,
"litellm_provider": "bedrock_converse",
@@ -18416,7 +19405,7 @@
"input_cost_per_token": 1.75e-06,
"input_cost_per_token_priority": 3.5e-06,
"litellm_provider": "openai",
- "max_input_tokens": 400000,
+ "max_input_tokens": 272000,
"max_output_tokens": 128000,
"max_tokens": 128000,
"mode": "responses",
@@ -20356,6 +21345,7 @@
"supports_function_calling": true,
"supports_tool_choice": true,
"supports_prompt_caching": true,
+ "supports_reasoning": true,
"supports_system_messages": true,
"max_input_tokens": 1000000,
"max_output_tokens": 8192
@@ -20370,6 +21360,7 @@
"supports_function_calling": true,
"supports_tool_choice": true,
"supports_prompt_caching": true,
+ "supports_reasoning": true,
"supports_system_messages": true,
"max_input_tokens": 1000000,
"max_output_tokens": 8192
@@ -20384,6 +21375,7 @@
"supports_function_calling": true,
"supports_tool_choice": true,
"supports_prompt_caching": true,
+ "supports_reasoning": true,
"supports_system_messages": true,
"max_input_tokens": 200000,
"max_output_tokens": 8192
@@ -21079,6 +22071,20 @@
"supports_tool_choice": true,
"supports_web_search": true
},
+ "moonshot/kimi-k2.5": {
+ "cache_read_input_token_cost": 1e-07,
+ "input_cost_per_token": 6e-07,
+ "litellm_provider": "moonshot",
+ "max_input_tokens": 262144,
+ "max_output_tokens": 262144,
+ "max_tokens": 262144,
+ "mode": "chat",
+ "output_cost_per_token": 3e-06,
+ "source": "https://platform.moonshot.ai/docs/pricing/chat",
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_vision": true
+ },
"moonshot/kimi-latest": {
"cache_read_input_token_cost": 1.5e-07,
"input_cost_per_token": 2e-06,
@@ -22971,6 +23977,7 @@
"supports_tool_choice": true
},
"openrouter/google/gemini-2.0-flash-001": {
+ "deprecation_date": "2026-03-31",
"input_cost_per_audio_token": 7e-07,
"input_cost_per_token": 1e-07,
"litellm_provider": "openrouter",
@@ -23267,7 +24274,7 @@
"mode": "chat",
"output_cost_per_token": 1.02e-06,
"supports_function_calling": true,
- "supports_prompt_caching": false,
+ "supports_prompt_caching": true,
"supports_reasoning": true,
"supports_tool_choice": true
},
@@ -23403,6 +24410,20 @@
"output_cost_per_token": 6.5e-07,
"supports_tool_choice": true
},
+ "openrouter/moonshotai/kimi-k2.5": {
+ "cache_read_input_token_cost": 1e-07,
+ "input_cost_per_token": 6e-07,
+ "litellm_provider": "openrouter",
+ "max_input_tokens": 262144,
+ "max_output_tokens": 262144,
+ "max_tokens": 262144,
+ "mode": "chat",
+ "output_cost_per_token": 3e-06,
+ "source": "https://openrouter.ai/moonshotai/kimi-k2.5",
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_vision": true
+ },
"openrouter/nousresearch/nous-hermes-llama2-13b": {
"input_cost_per_token": 2e-07,
"litellm_provider": "openrouter",
@@ -23616,11 +24637,14 @@
"cache_read_input_token_cost": 1.75e-07,
"input_cost_per_token": 1.75e-06,
"litellm_provider": "openrouter",
- "max_input_tokens": 400000,
+ "max_input_tokens": 272000,
"max_output_tokens": 128000,
"max_tokens": 128000,
- "mode": "chat",
+ "mode": "responses",
"output_cost_per_token": 1.4e-05,
+ "supported_endpoints": [
+ "/v1/responses"
+ ],
"supported_modalities": [
"text",
"image"
@@ -23902,6 +24926,31 @@
"supports_tool_choice": true,
"supports_function_calling": true
},
+ "openrouter/qwen/qwen3-235b-a22b-2507": {
+ "input_cost_per_token": 7.1e-08,
+ "litellm_provider": "openrouter",
+ "max_input_tokens": 262144,
+ "max_output_tokens": 262144,
+ "max_tokens": 262144,
+ "mode": "chat",
+ "output_cost_per_token": 1e-07,
+ "source": "https://openrouter.ai/qwen/qwen3-235b-a22b-2507",
+ "supports_function_calling": true,
+ "supports_tool_choice": true
+ },
+ "openrouter/qwen/qwen3-235b-a22b-thinking-2507": {
+ "input_cost_per_token": 1.1e-07,
+ "litellm_provider": "openrouter",
+ "max_input_tokens": 262144,
+ "max_output_tokens": 262144,
+ "max_tokens": 262144,
+ "mode": "chat",
+ "output_cost_per_token": 6e-07,
+ "source": "https://openrouter.ai/qwen/qwen3-235b-a22b-thinking-2507",
+ "supports_function_calling": true,
+ "supports_reasoning": true,
+ "supports_tool_choice": true
+ },
"openrouter/switchpoint/router": {
"input_cost_per_token": 8.5e-07,
"litellm_provider": "openrouter",
@@ -23959,6 +25008,7 @@
"output_cost_per_token": 1.75e-06,
"source": "https://openrouter.ai/z-ai/glm-4.6",
"supports_function_calling": true,
+ "supports_prompt_caching": true,
"supports_reasoning": true,
"supports_tool_choice": true
},
@@ -23972,9 +25022,76 @@
"output_cost_per_token": 1.9e-06,
"source": "https://openrouter.ai/z-ai/glm-4.6:exacto",
"supports_function_calling": true,
+ "supports_prompt_caching": true,
"supports_reasoning": true,
"supports_tool_choice": true
},
+ "openrouter/xiaomi/mimo-v2-flash": {
+ "input_cost_per_token": 9e-08,
+ "output_cost_per_token": 2.9e-07,
+ "cache_creation_input_token_cost": 0.0,
+ "cache_read_input_token_cost": 0.0,
+ "litellm_provider": "openrouter",
+ "max_input_tokens": 262144,
+ "max_output_tokens": 16384,
+ "max_tokens": 16384,
+ "mode": "chat",
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_reasoning": true,
+ "supports_vision": false,
+ "supports_prompt_caching": false
+ },
+ "openrouter/z-ai/glm-4.7": {
+ "input_cost_per_token": 4e-07,
+ "output_cost_per_token": 1.5e-06,
+ "cache_creation_input_token_cost": 0.0,
+ "cache_read_input_token_cost": 0.0,
+ "litellm_provider": "openrouter",
+ "max_input_tokens": 202752,
+ "max_output_tokens": 64000,
+ "max_tokens": 64000,
+ "mode": "chat",
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_reasoning": true,
+ "supports_vision": true,
+ "supports_prompt_caching": false,
+ "supports_assistant_prefill": true
+ },
+ "openrouter/z-ai/glm-4.7-flash": {
+ "input_cost_per_token": 7e-08,
+ "output_cost_per_token": 4e-07,
+ "cache_creation_input_token_cost": 0.0,
+ "cache_read_input_token_cost": 0.0,
+ "litellm_provider": "openrouter",
+ "max_input_tokens": 200000,
+ "max_output_tokens": 32000,
+ "max_tokens": 32000,
+ "mode": "chat",
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_reasoning": true,
+ "supports_vision": true,
+ "supports_prompt_caching": false
+ },
+ "openrouter/minimax/minimax-m2.1": {
+ "input_cost_per_token": 2.7e-07,
+ "output_cost_per_token": 1.2e-06,
+ "cache_creation_input_token_cost": 0.0,
+ "cache_read_input_token_cost": 0.0,
+ "litellm_provider": "openrouter",
+ "max_input_tokens": 204000,
+ "max_output_tokens": 64000,
+ "max_tokens": 64000,
+ "mode": "chat",
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_reasoning": true,
+ "supports_vision": true,
+ "supports_prompt_caching": false,
+ "supports_computer_use": false
+ },
"ovhcloud/DeepSeek-R1-Distill-Llama-70B": {
"input_cost_per_token": 6.7e-07,
"litellm_provider": "ovhcloud",
@@ -25839,13 +26956,13 @@
"litellm_provider": "bedrock",
"max_input_tokens": 77,
"mode": "image_edit",
- "output_cost_per_image": 0.40
+ "output_cost_per_image": 0.4
},
"stability.stable-creative-upscale-v1:0": {
"litellm_provider": "bedrock",
"max_input_tokens": 77,
"mode": "image_edit",
- "output_cost_per_image": 0.60
+ "output_cost_per_image": 0.6
},
"stability.stable-fast-upscale-v1:0": {
"litellm_provider": "bedrock",
@@ -26604,6 +27721,34 @@
"supports_reasoning": true,
"supports_tool_choice": true
},
+ "together_ai/zai-org/GLM-4.7": {
+ "input_cost_per_token": 4.5e-07,
+ "litellm_provider": "together_ai",
+ "max_input_tokens": 200000,
+ "max_output_tokens": 200000,
+ "max_tokens": 200000,
+ "mode": "chat",
+ "output_cost_per_token": 2e-06,
+ "source": "https://www.together.ai/models/glm-4-7",
+ "supports_function_calling": true,
+ "supports_parallel_function_calling": true,
+ "supports_reasoning": true,
+ "supports_tool_choice": true
+ },
+ "together_ai/moonshotai/Kimi-K2.5": {
+ "input_cost_per_token": 5e-07,
+ "litellm_provider": "together_ai",
+ "max_input_tokens": 256000,
+ "max_output_tokens": 256000,
+ "max_tokens": 256000,
+ "mode": "chat",
+ "output_cost_per_token": 2.8e-06,
+ "source": "https://www.together.ai/models/kimi-k2-5",
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "supports_reasoning": true
+ },
"together_ai/moonshotai/Kimi-K2-Instruct-0905": {
"input_cost_per_token": 1e-06,
"litellm_provider": "together_ai",
@@ -27320,7 +28465,9 @@
"max_output_tokens": 16384,
"max_tokens": 16384,
"mode": "chat",
- "output_cost_per_token": 3e-07
+ "output_cost_per_token": 3e-07,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/alibaba/qwen3-coder": {
"input_cost_per_token": 4e-07,
@@ -27329,7 +28476,9 @@
"max_output_tokens": 66536,
"max_tokens": 66536,
"mode": "chat",
- "output_cost_per_token": 1.6e-06
+ "output_cost_per_token": 1.6e-06,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/amazon/nova-lite": {
"input_cost_per_token": 6e-08,
@@ -27338,7 +28487,10 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 2.4e-07
+ "output_cost_per_token": 2.4e-07,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/amazon/nova-micro": {
"input_cost_per_token": 3.5e-08,
@@ -27347,7 +28499,9 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 1.4e-07
+ "output_cost_per_token": 1.4e-07,
+ "supports_function_calling": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/amazon/nova-pro": {
"input_cost_per_token": 8e-07,
@@ -27356,7 +28510,10 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 3.2e-06
+ "output_cost_per_token": 3.2e-06,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/amazon/titan-embed-text-v2": {
"input_cost_per_token": 2e-08,
@@ -27376,7 +28533,11 @@
"max_output_tokens": 4096,
"max_tokens": 4096,
"mode": "chat",
- "output_cost_per_token": 1.25e-06
+ "output_cost_per_token": 1.25e-06,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/anthropic/claude-3-opus": {
"cache_creation_input_token_cost": 1.875e-05,
@@ -27387,7 +28548,11 @@
"max_output_tokens": 4096,
"max_tokens": 4096,
"mode": "chat",
- "output_cost_per_token": 7.5e-05
+ "output_cost_per_token": 7.5e-05,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/anthropic/claude-3.5-haiku": {
"cache_creation_input_token_cost": 1e-06,
@@ -27398,7 +28563,11 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 4e-06
+ "output_cost_per_token": 4e-06,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/anthropic/claude-3.5-sonnet": {
"cache_creation_input_token_cost": 3.75e-06,
@@ -27409,7 +28578,11 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 1.5e-05
+ "output_cost_per_token": 1.5e-05,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/anthropic/claude-3.7-sonnet": {
"cache_creation_input_token_cost": 3.75e-06,
@@ -27420,7 +28593,11 @@
"max_output_tokens": 64000,
"max_tokens": 64000,
"mode": "chat",
- "output_cost_per_token": 1.5e-05
+ "output_cost_per_token": 1.5e-05,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/anthropic/claude-4-opus": {
"cache_creation_input_token_cost": 1.875e-05,
@@ -27431,7 +28608,11 @@
"max_output_tokens": 32000,
"max_tokens": 32000,
"mode": "chat",
- "output_cost_per_token": 7.5e-05
+ "output_cost_per_token": 7.5e-05,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/anthropic/claude-4-sonnet": {
"cache_creation_input_token_cost": 3.75e-06,
@@ -27442,7 +28623,9 @@
"max_output_tokens": 64000,
"max_tokens": 64000,
"mode": "chat",
- "output_cost_per_token": 1.5e-05
+ "output_cost_per_token": 1.5e-05,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/cohere/command-a": {
"input_cost_per_token": 2.5e-06,
@@ -27451,7 +28634,9 @@
"max_output_tokens": 8000,
"max_tokens": 8000,
"mode": "chat",
- "output_cost_per_token": 1e-05
+ "output_cost_per_token": 1e-05,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/cohere/command-r": {
"input_cost_per_token": 1.5e-07,
@@ -27460,7 +28645,9 @@
"max_output_tokens": 4096,
"max_tokens": 4096,
"mode": "chat",
- "output_cost_per_token": 6e-07
+ "output_cost_per_token": 6e-07,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/cohere/command-r-plus": {
"input_cost_per_token": 2.5e-06,
@@ -27469,7 +28656,9 @@
"max_output_tokens": 4096,
"max_tokens": 4096,
"mode": "chat",
- "output_cost_per_token": 1e-05
+ "output_cost_per_token": 1e-05,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/cohere/embed-v4.0": {
"input_cost_per_token": 1.2e-07,
@@ -27487,7 +28676,8 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 2.19e-06
+ "output_cost_per_token": 2.19e-06,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/deepseek/deepseek-r1-distill-llama-70b": {
"input_cost_per_token": 7.5e-07,
@@ -27496,7 +28686,10 @@
"max_output_tokens": 131072,
"max_tokens": 131072,
"mode": "chat",
- "output_cost_per_token": 9.9e-07
+ "output_cost_per_token": 9.9e-07,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/deepseek/deepseek-v3": {
"input_cost_per_token": 9e-07,
@@ -27505,25 +28698,36 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 9e-07
+ "output_cost_per_token": 9e-07,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/google/gemini-2.0-flash": {
+ "deprecation_date": "2026-03-31",
"input_cost_per_token": 1.5e-07,
"litellm_provider": "vercel_ai_gateway",
"max_input_tokens": 1048576,
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 6e-07
+ "output_cost_per_token": 6e-07,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/google/gemini-2.0-flash-lite": {
+ "deprecation_date": "2026-03-31",
"input_cost_per_token": 7.5e-08,
"litellm_provider": "vercel_ai_gateway",
"max_input_tokens": 1048576,
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 3e-07
+ "output_cost_per_token": 3e-07,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/google/gemini-2.5-flash": {
"input_cost_per_token": 3e-07,
@@ -27532,7 +28736,11 @@
"max_output_tokens": 65536,
"max_tokens": 65536,
"mode": "chat",
- "output_cost_per_token": 2.5e-06
+ "output_cost_per_token": 2.5e-06,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/google/gemini-2.5-pro": {
"input_cost_per_token": 2.5e-06,
@@ -27541,7 +28749,11 @@
"max_output_tokens": 65536,
"max_tokens": 65536,
"mode": "chat",
- "output_cost_per_token": 1e-05
+ "output_cost_per_token": 1e-05,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/google/gemini-embedding-001": {
"input_cost_per_token": 1.5e-07,
@@ -27559,7 +28771,10 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 2e-07
+ "output_cost_per_token": 2e-07,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/google/text-embedding-005": {
"input_cost_per_token": 2.5e-08,
@@ -27595,7 +28810,8 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 7.9e-07
+ "output_cost_per_token": 7.9e-07,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/meta/llama-3-8b": {
"input_cost_per_token": 5e-08,
@@ -27604,7 +28820,8 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 8e-08
+ "output_cost_per_token": 8e-08,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/meta/llama-3.1-70b": {
"input_cost_per_token": 7.2e-07,
@@ -27613,7 +28830,8 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 7.2e-07
+ "output_cost_per_token": 7.2e-07,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/meta/llama-3.1-8b": {
"input_cost_per_token": 5e-08,
@@ -27622,7 +28840,9 @@
"max_output_tokens": 131072,
"max_tokens": 131072,
"mode": "chat",
- "output_cost_per_token": 8e-08
+ "output_cost_per_token": 8e-08,
+ "supports_function_calling": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/meta/llama-3.2-11b": {
"input_cost_per_token": 1.6e-07,
@@ -27631,7 +28851,10 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 1.6e-07
+ "output_cost_per_token": 1.6e-07,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/meta/llama-3.2-1b": {
"input_cost_per_token": 1e-07,
@@ -27649,7 +28872,9 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 1.5e-07
+ "output_cost_per_token": 1.5e-07,
+ "supports_function_calling": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/meta/llama-3.2-90b": {
"input_cost_per_token": 7.2e-07,
@@ -27658,7 +28883,10 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 7.2e-07
+ "output_cost_per_token": 7.2e-07,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/meta/llama-3.3-70b": {
"input_cost_per_token": 7.2e-07,
@@ -27667,7 +28895,9 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 7.2e-07
+ "output_cost_per_token": 7.2e-07,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/meta/llama-4-maverick": {
"input_cost_per_token": 2e-07,
@@ -27676,7 +28906,8 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 6e-07
+ "output_cost_per_token": 6e-07,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/meta/llama-4-scout": {
"input_cost_per_token": 1e-07,
@@ -27685,7 +28916,10 @@
"max_output_tokens": 8192,
"max_tokens": 8192,
"mode": "chat",
- "output_cost_per_token": 3e-07
+ "output_cost_per_token": 3e-07,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/mistral/codestral": {
"input_cost_per_token": 3e-07,
@@ -27694,7 +28928,9 @@
"max_output_tokens": 4000,
"max_tokens": 4000,
"mode": "chat",
- "output_cost_per_token": 9e-07
+ "output_cost_per_token": 9e-07,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/mistral/codestral-embed": {
"input_cost_per_token": 1.5e-07,
@@ -27712,7 +28948,10 @@
"max_output_tokens": 128000,
"max_tokens": 128000,
"mode": "chat",
- "output_cost_per_token": 2.8e-07
+ "output_cost_per_token": 2.8e-07,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/mistral/magistral-medium": {
"input_cost_per_token": 2e-06,
@@ -27721,7 +28960,10 @@
"max_output_tokens": 64000,
"max_tokens": 64000,
"mode": "chat",
- "output_cost_per_token": 5e-06
+ "output_cost_per_token": 5e-06,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/mistral/magistral-small": {
"input_cost_per_token": 5e-07,
@@ -27730,7 +28972,8 @@
"max_output_tokens": 64000,
"max_tokens": 64000,
"mode": "chat",
- "output_cost_per_token": 1.5e-06
+ "output_cost_per_token": 1.5e-06,
+ "supports_function_calling": true
},
"vercel_ai_gateway/mistral/ministral-3b": {
"input_cost_per_token": 4e-08,
@@ -27739,7 +28982,9 @@
"max_output_tokens": 4000,
"max_tokens": 4000,
"mode": "chat",
- "output_cost_per_token": 4e-08
+ "output_cost_per_token": 4e-08,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/mistral/ministral-8b": {
"input_cost_per_token": 1e-07,
@@ -27748,7 +28993,10 @@
"max_output_tokens": 4000,
"max_tokens": 4000,
"mode": "chat",
- "output_cost_per_token": 1e-07
+ "output_cost_per_token": 1e-07,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/mistral/mistral-embed": {
"input_cost_per_token": 1e-07,
@@ -27766,7 +29014,9 @@
"max_output_tokens": 4000,
"max_tokens": 4000,
"mode": "chat",
- "output_cost_per_token": 6e-06
+ "output_cost_per_token": 6e-06,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/mistral/mistral-saba-24b": {
"input_cost_per_token": 7.9e-07,
@@ -27784,7 +29034,10 @@
"max_output_tokens": 4000,
"max_tokens": 4000,
"mode": "chat",
- "output_cost_per_token": 3e-07
+ "output_cost_per_token": 3e-07,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/mistral/mixtral-8x22b-instruct": {
"input_cost_per_token": 1.2e-06,
@@ -27793,7 +29046,8 @@
"max_output_tokens": 2048,
"max_tokens": 2048,
"mode": "chat",
- "output_cost_per_token": 1.2e-06
+ "output_cost_per_token": 1.2e-06,
+ "supports_function_calling": true
},
"vercel_ai_gateway/mistral/pixtral-12b": {
"input_cost_per_token": 1.5e-07,
@@ -27802,7 +29056,11 @@
"max_output_tokens": 4000,
"max_tokens": 4000,
"mode": "chat",
- "output_cost_per_token": 1.5e-07
+ "output_cost_per_token": 1.5e-07,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/mistral/pixtral-large": {
"input_cost_per_token": 2e-06,
@@ -27811,7 +29069,11 @@
"max_output_tokens": 4000,
"max_tokens": 4000,
"mode": "chat",
- "output_cost_per_token": 6e-06
+ "output_cost_per_token": 6e-06,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/moonshotai/kimi-k2": {
"input_cost_per_token": 5.5e-07,
@@ -27820,7 +29082,9 @@
"max_output_tokens": 16384,
"max_tokens": 16384,
"mode": "chat",
- "output_cost_per_token": 2.2e-06
+ "output_cost_per_token": 2.2e-06,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/morph/morph-v3-fast": {
"input_cost_per_token": 8e-07,
@@ -27847,7 +29111,9 @@
"max_output_tokens": 4096,
"max_tokens": 4096,
"mode": "chat",
- "output_cost_per_token": 1.5e-06
+ "output_cost_per_token": 1.5e-06,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/openai/gpt-3.5-turbo-instruct": {
"input_cost_per_token": 1.5e-06,
@@ -27865,7 +29131,10 @@
"max_output_tokens": 4096,
"max_tokens": 4096,
"mode": "chat",
- "output_cost_per_token": 3e-05
+ "output_cost_per_token": 3e-05,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/openai/gpt-4.1": {
"cache_creation_input_token_cost": 0.0,
@@ -27876,7 +29145,11 @@
"max_output_tokens": 32768,
"max_tokens": 32768,
"mode": "chat",
- "output_cost_per_token": 8e-06
+ "output_cost_per_token": 8e-06,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/openai/gpt-4.1-mini": {
"cache_creation_input_token_cost": 0.0,
@@ -27887,7 +29160,11 @@
"max_output_tokens": 32768,
"max_tokens": 32768,
"mode": "chat",
- "output_cost_per_token": 1.6e-06
+ "output_cost_per_token": 1.6e-06,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/openai/gpt-4.1-nano": {
"cache_creation_input_token_cost": 0.0,
@@ -27898,7 +29175,11 @@
"max_output_tokens": 32768,
"max_tokens": 32768,
"mode": "chat",
- "output_cost_per_token": 4e-07
+ "output_cost_per_token": 4e-07,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/openai/gpt-4o": {
"cache_creation_input_token_cost": 0.0,
@@ -27909,7 +29190,11 @@
"max_output_tokens": 16384,
"max_tokens": 16384,
"mode": "chat",
- "output_cost_per_token": 1e-05
+ "output_cost_per_token": 1e-05,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/openai/gpt-4o-mini": {
"cache_creation_input_token_cost": 0.0,
@@ -27920,7 +29205,11 @@
"max_output_tokens": 16384,
"max_tokens": 16384,
"mode": "chat",
- "output_cost_per_token": 6e-07
+ "output_cost_per_token": 6e-07,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/openai/o1": {
"cache_creation_input_token_cost": 0.0,
@@ -27931,7 +29220,11 @@
"max_output_tokens": 100000,
"max_tokens": 100000,
"mode": "chat",
- "output_cost_per_token": 6e-05
+ "output_cost_per_token": 6e-05,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/openai/o3": {
"cache_creation_input_token_cost": 0.0,
@@ -27942,7 +29235,11 @@
"max_output_tokens": 100000,
"max_tokens": 100000,
"mode": "chat",
- "output_cost_per_token": 8e-06
+ "output_cost_per_token": 8e-06,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/openai/o3-mini": {
"cache_creation_input_token_cost": 0.0,
@@ -27953,7 +29250,10 @@
"max_output_tokens": 100000,
"max_tokens": 100000,
"mode": "chat",
- "output_cost_per_token": 4.4e-06
+ "output_cost_per_token": 4.4e-06,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/openai/o4-mini": {
"cache_creation_input_token_cost": 0.0,
@@ -27964,7 +29264,11 @@
"max_output_tokens": 100000,
"max_tokens": 100000,
"mode": "chat",
- "output_cost_per_token": 4.4e-06
+ "output_cost_per_token": 4.4e-06,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true,
+ "supports_response_schema": true
},
"vercel_ai_gateway/openai/text-embedding-3-large": {
"input_cost_per_token": 1.3e-07,
@@ -28036,7 +29340,10 @@
"max_output_tokens": 32000,
"max_tokens": 32000,
"mode": "chat",
- "output_cost_per_token": 1.5e-05
+ "output_cost_per_token": 1.5e-05,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/vercel/v0-1.5-md": {
"input_cost_per_token": 3e-06,
@@ -28045,7 +29352,10 @@
"max_output_tokens": 32768,
"max_tokens": 32768,
"mode": "chat",
- "output_cost_per_token": 1.5e-05
+ "output_cost_per_token": 1.5e-05,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/xai/grok-2": {
"input_cost_per_token": 2e-06,
@@ -28054,7 +29364,9 @@
"max_output_tokens": 4000,
"max_tokens": 4000,
"mode": "chat",
- "output_cost_per_token": 1e-05
+ "output_cost_per_token": 1e-05,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/xai/grok-2-vision": {
"input_cost_per_token": 2e-06,
@@ -28063,7 +29375,10 @@
"max_output_tokens": 32768,
"max_tokens": 32768,
"mode": "chat",
- "output_cost_per_token": 1e-05
+ "output_cost_per_token": 1e-05,
+ "supports_vision": true,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/xai/grok-3": {
"input_cost_per_token": 3e-06,
@@ -28072,7 +29387,9 @@
"max_output_tokens": 131072,
"max_tokens": 131072,
"mode": "chat",
- "output_cost_per_token": 1.5e-05
+ "output_cost_per_token": 1.5e-05,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/xai/grok-3-fast": {
"input_cost_per_token": 5e-06,
@@ -28081,7 +29398,8 @@
"max_output_tokens": 131072,
"max_tokens": 131072,
"mode": "chat",
- "output_cost_per_token": 2.5e-05
+ "output_cost_per_token": 2.5e-05,
+ "supports_function_calling": true
},
"vercel_ai_gateway/xai/grok-3-mini": {
"input_cost_per_token": 3e-07,
@@ -28090,7 +29408,9 @@
"max_output_tokens": 131072,
"max_tokens": 131072,
"mode": "chat",
- "output_cost_per_token": 5e-07
+ "output_cost_per_token": 5e-07,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/xai/grok-3-mini-fast": {
"input_cost_per_token": 6e-07,
@@ -28099,7 +29419,9 @@
"max_output_tokens": 131072,
"max_tokens": 131072,
"mode": "chat",
- "output_cost_per_token": 4e-06
+ "output_cost_per_token": 4e-06,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/xai/grok-4": {
"input_cost_per_token": 3e-06,
@@ -28108,7 +29430,9 @@
"max_output_tokens": 256000,
"max_tokens": 256000,
"mode": "chat",
- "output_cost_per_token": 1.5e-05
+ "output_cost_per_token": 1.5e-05,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/zai/glm-4.5": {
"input_cost_per_token": 6e-07,
@@ -28117,7 +29441,9 @@
"max_output_tokens": 131072,
"max_tokens": 131072,
"mode": "chat",
- "output_cost_per_token": 2.2e-06
+ "output_cost_per_token": 2.2e-06,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/zai/glm-4.5-air": {
"input_cost_per_token": 2e-07,
@@ -28126,7 +29452,9 @@
"max_output_tokens": 96000,
"max_tokens": 96000,
"mode": "chat",
- "output_cost_per_token": 1.1e-06
+ "output_cost_per_token": 1.1e-06,
+ "supports_function_calling": true,
+ "supports_tool_choice": true
},
"vercel_ai_gateway/zai/glm-4.6": {
"litellm_provider": "vercel_ai_gateway",
@@ -28194,7 +29522,9 @@
"supports_prompt_caching": true,
"supports_reasoning": true,
"supports_response_schema": true,
- "supports_tool_choice": true
+ "supports_tool_choice": true,
+ "supports_native_streaming": true,
+ "supports_vision": true
},
"vertex_ai/claude-3-5-sonnet": {
"input_cost_per_token": 3e-06,
@@ -28465,7 +29795,38 @@
"supports_response_schema": true,
"supports_tool_choice": true,
"supports_vision": true,
- "tool_use_system_prompt_tokens": 159
+ "tool_use_system_prompt_tokens": 159,
+ "supports_native_streaming": true
+ },
+ "vertex_ai/claude-opus-4-6": {
+ "cache_creation_input_token_cost": 6.25e-06,
+ "cache_creation_input_token_cost_above_200k_tokens": 1.25e-05,
+ "cache_read_input_token_cost": 5e-07,
+ "cache_read_input_token_cost_above_200k_tokens": 1e-06,
+ "input_cost_per_token": 5e-06,
+ "input_cost_per_token_above_200k_tokens": 1e-05,
+ "litellm_provider": "vertex_ai-anthropic_models",
+ "max_input_tokens": 1000000,
+ "max_output_tokens": 128000,
+ "max_tokens": 128000,
+ "mode": "chat",
+ "output_cost_per_token": 2.5e-05,
+ "output_cost_per_token_above_200k_tokens": 3.75e-05,
+ "search_context_cost_per_query": {
+ "search_context_size_high": 0.01,
+ "search_context_size_low": 0.01,
+ "search_context_size_medium": 0.01
+ },
+ "supports_assistant_prefill": false,
+ "supports_computer_use": true,
+ "supports_function_calling": true,
+ "supports_pdf_input": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
+ "supports_response_schema": true,
+ "supports_tool_choice": true,
+ "supports_vision": true,
+ "tool_use_system_prompt_tokens": 346
},
"vertex_ai/claude-sonnet-4-5": {
"cache_creation_input_token_cost": 3.75e-06,
@@ -28517,7 +29878,8 @@
"supports_reasoning": true,
"supports_response_schema": true,
"supports_tool_choice": true,
- "supports_vision": true
+ "supports_vision": true,
+ "supports_native_streaming": true
},
"vertex_ai/claude-opus-4@20250514": {
"cache_creation_input_token_cost": 1.875e-05,
@@ -28799,6 +30161,21 @@
"output_cost_per_token_batches": 6e-06,
"source": "https://docs.cloud.google.com/vertex-ai/generative-ai/docs/models/gemini/3-pro-image"
},
+ "vertex_ai/deep-research-pro-preview-12-2025": {
+ "input_cost_per_image": 0.0011,
+ "input_cost_per_token": 2e-06,
+ "input_cost_per_token_batches": 1e-06,
+ "litellm_provider": "vertex_ai-language-models",
+ "max_input_tokens": 65536,
+ "max_output_tokens": 32768,
+ "max_tokens": 32768,
+ "mode": "image_generation",
+ "output_cost_per_image": 0.134,
+ "output_cost_per_image_token": 0.00012,
+ "output_cost_per_token": 1.2e-05,
+ "output_cost_per_token_batches": 6e-06,
+ "source": "https://docs.cloud.google.com/vertex-ai/generative-ai/docs/models/gemini/3-pro-image"
+ },
"vertex_ai/imagegeneration@006": {
"litellm_provider": "vertex_ai-image-models",
"mode": "image_generation",
@@ -29288,6 +30665,9 @@
"mode": "chat",
"output_cost_per_token": 1e-06,
"source": "https://cloud.google.com/vertex-ai/generative-ai/pricing",
+ "supported_regions": [
+ "global"
+ ],
"supports_function_calling": true,
"supports_tool_choice": true
},
@@ -29300,6 +30680,9 @@
"mode": "chat",
"output_cost_per_token": 4e-06,
"source": "https://cloud.google.com/vertex-ai/generative-ai/pricing",
+ "supported_regions": [
+ "global"
+ ],
"supports_function_calling": true,
"supports_tool_choice": true
},
@@ -29312,6 +30695,9 @@
"mode": "chat",
"output_cost_per_token": 1.2e-06,
"source": "https://cloud.google.com/vertex-ai/generative-ai/pricing",
+ "supported_regions": [
+ "global"
+ ],
"supports_function_calling": true,
"supports_tool_choice": true
},
@@ -29324,6 +30710,9 @@
"mode": "chat",
"output_cost_per_token": 1.2e-06,
"source": "https://cloud.google.com/vertex-ai/generative-ai/pricing",
+ "supported_regions": [
+ "global"
+ ],
"supports_function_calling": true,
"supports_tool_choice": true
},
@@ -30186,6 +31575,7 @@
"supports_web_search": true
},
"xai/grok-3": {
+ "cache_read_input_token_cost": 7.5e-07,
"input_cost_per_token": 3e-06,
"litellm_provider": "xai",
"max_input_tokens": 131072,
@@ -30200,6 +31590,7 @@
"supports_web_search": true
},
"xai/grok-3-beta": {
+ "cache_read_input_token_cost": 7.5e-07,
"input_cost_per_token": 3e-06,
"litellm_provider": "xai",
"max_input_tokens": 131072,
@@ -30214,6 +31605,7 @@
"supports_web_search": true
},
"xai/grok-3-fast-beta": {
+ "cache_read_input_token_cost": 1.25e-06,
"input_cost_per_token": 5e-06,
"litellm_provider": "xai",
"max_input_tokens": 131072,
@@ -30228,6 +31620,7 @@
"supports_web_search": true
},
"xai/grok-3-fast-latest": {
+ "cache_read_input_token_cost": 1.25e-06,
"input_cost_per_token": 5e-06,
"litellm_provider": "xai",
"max_input_tokens": 131072,
@@ -30242,6 +31635,7 @@
"supports_web_search": true
},
"xai/grok-3-latest": {
+ "cache_read_input_token_cost": 7.5e-07,
"input_cost_per_token": 3e-06,
"litellm_provider": "xai",
"max_input_tokens": 131072,
@@ -30256,6 +31650,7 @@
"supports_web_search": true
},
"xai/grok-3-mini": {
+ "cache_read_input_token_cost": 7.5e-08,
"input_cost_per_token": 3e-07,
"litellm_provider": "xai",
"max_input_tokens": 131072,
@@ -30271,6 +31666,7 @@
"supports_web_search": true
},
"xai/grok-3-mini-beta": {
+ "cache_read_input_token_cost": 7.5e-08,
"input_cost_per_token": 3e-07,
"litellm_provider": "xai",
"max_input_tokens": 131072,
@@ -30286,6 +31682,7 @@
"supports_web_search": true
},
"xai/grok-3-mini-fast": {
+ "cache_read_input_token_cost": 1.5e-07,
"input_cost_per_token": 6e-07,
"litellm_provider": "xai",
"max_input_tokens": 131072,
@@ -30301,6 +31698,7 @@
"supports_web_search": true
},
"xai/grok-3-mini-fast-beta": {
+ "cache_read_input_token_cost": 1.5e-07,
"input_cost_per_token": 6e-07,
"litellm_provider": "xai",
"max_input_tokens": 131072,
@@ -30316,6 +31714,7 @@
"supports_web_search": true
},
"xai/grok-3-mini-fast-latest": {
+ "cache_read_input_token_cost": 1.5e-07,
"input_cost_per_token": 6e-07,
"litellm_provider": "xai",
"max_input_tokens": 131072,
@@ -30331,6 +31730,7 @@
"supports_web_search": true
},
"xai/grok-3-mini-latest": {
+ "cache_read_input_token_cost": 7.5e-08,
"input_cost_per_token": 3e-07,
"litellm_provider": "xai",
"max_input_tokens": 131072,
@@ -30597,11 +31997,14 @@
"max_output_tokens": 128000,
"mode": "chat",
"supports_function_calling": true,
+ "supports_prompt_caching": true,
"supports_reasoning": true,
"supports_tool_choice": true,
"source": "https://docs.z.ai/guides/overview/pricing"
},
"zai/glm-4.6": {
+ "cache_creation_input_token_cost": 0,
+ "cache_read_input_token_cost": 1.1e-07,
"input_cost_per_token": 6e-07,
"output_cost_per_token": 2.2e-06,
"litellm_provider": "zai",
@@ -30609,6 +32012,8 @@
"max_output_tokens": 128000,
"mode": "chat",
"supports_function_calling": true,
+ "supports_prompt_caching": true,
+ "supports_reasoning": true,
"supports_tool_choice": true,
"source": "https://docs.z.ai/guides/overview/pricing"
},
diff --git a/litellm/proxy/_experimental/mcp_server/auth/litellm_auth_handler.py b/litellm/proxy/_experimental/mcp_server/auth/litellm_auth_handler.py
index 081d83dd1c8..75b75d3ba44 100644
--- a/litellm/proxy/_experimental/mcp_server/auth/litellm_auth_handler.py
+++ b/litellm/proxy/_experimental/mcp_server/auth/litellm_auth_handler.py
@@ -27,6 +27,7 @@ class MCPAuthenticatedUser(AuthenticatedUser):
oauth2_headers: Optional[Dict[str, str]] = None,
mcp_protocol_version: Optional[str] = None,
raw_headers: Optional[Dict[str, str]] = None,
+ client_ip: Optional[str] = None,
):
self.user_api_key_auth = user_api_key_auth
self.mcp_auth_header = mcp_auth_header
@@ -35,3 +36,4 @@ class MCPAuthenticatedUser(AuthenticatedUser):
self.mcp_protocol_version = mcp_protocol_version
self.oauth2_headers = oauth2_headers
self.raw_headers = raw_headers
+ self.client_ip = client_ip
diff --git a/litellm/proxy/_experimental/mcp_server/auth/user_api_key_auth_mcp.py b/litellm/proxy/_experimental/mcp_server/auth/user_api_key_auth_mcp.py
index 49d6ac7d898..786cfbfb008 100644
--- a/litellm/proxy/_experimental/mcp_server/auth/user_api_key_auth_mcp.py
+++ b/litellm/proxy/_experimental/mcp_server/auth/user_api_key_auth_mcp.py
@@ -1,11 +1,12 @@
from typing import Dict, List, Optional, Set, Tuple
+from fastapi import HTTPException
from starlette.datastructures import Headers
from starlette.requests import Request
from starlette.types import Scope
from litellm._logging import verbose_logger
-from litellm.proxy._types import LiteLLM_TeamTable, SpecialHeaders, UserAPIKeyAuth
+from litellm.proxy._types import LiteLLM_TeamTable, ProxyException, SpecialHeaders, UserAPIKeyAuth
from litellm.proxy.auth.user_api_key_auth import user_api_key_auth
@@ -63,6 +64,13 @@ class MCPRequestHandler:
HTTPException: If headers are invalid or missing required headers
"""
headers = MCPRequestHandler._safe_get_headers_from_scope(scope)
+
+ # Check if there is an explicit LiteLLM API key (primary header)
+ has_explicit_litellm_key = (
+ headers.get(MCPRequestHandler.LITELLM_API_KEY_HEADER_NAME_PRIMARY)
+ is not None
+ )
+
litellm_api_key = (
MCPRequestHandler.get_litellm_api_key_from_headers(headers) or ""
)
@@ -106,16 +114,38 @@ class MCPRequestHandler:
request.body = mock_body # type: ignore
if ".well-known" in str(request.url): # public routes
validated_user_api_key_auth = UserAPIKeyAuth()
- # elif litellm_api_key == "":
- # from fastapi import HTTPException
-
- # raise HTTPException(
- # status_code=401,
- # detail="LiteLLM API key is missing. Please add it or use OAuth authentication.",
- # headers={
- # "WWW-Authenticate": f'Bearer resource_metadata=f"{request.base_url}/.well-known/oauth-protected-resource"',
- # },
- # )
+ elif has_explicit_litellm_key:
+ # Explicit x-litellm-api-key provided - always validate normally
+ validated_user_api_key_auth = await user_api_key_auth(
+ api_key=litellm_api_key, request=request
+ )
+ elif oauth2_headers:
+ # No x-litellm-api-key, but Authorization header present.
+ # Could be a LiteLLM key (backward compat) OR an OAuth2 token
+ # from an upstream MCP provider (e.g. Atlassian).
+ # Try LiteLLM auth first; on auth failure, treat as OAuth2 passthrough.
+ try:
+ validated_user_api_key_auth = await user_api_key_auth(
+ api_key=litellm_api_key, request=request
+ )
+ except HTTPException as e:
+ if e.status_code in (401, 403):
+ verbose_logger.debug(
+ "MCP OAuth2: Authorization header is not a valid LiteLLM key, "
+ "treating as OAuth2 token passthrough"
+ )
+ validated_user_api_key_auth = UserAPIKeyAuth()
+ else:
+ raise
+ except ProxyException as e:
+ if str(e.code) in ("401", "403"):
+ verbose_logger.debug(
+ "MCP OAuth2: Authorization header is not a valid LiteLLM key, "
+ "treating as OAuth2 token passthrough"
+ )
+ validated_user_api_key_auth = UserAPIKeyAuth()
+ else:
+ raise
else:
validated_user_api_key_auth = await user_api_key_auth(
api_key=litellm_api_key, request=request
@@ -387,6 +417,9 @@ class MCPRequestHandler:
user_api_key_cache,
)
+ verbose_logger.debug(
+ f"MCP team permission lookup: team_id={user_api_key_auth.team_id if user_api_key_auth else None}"
+ )
if not user_api_key_auth or not user_api_key_auth.team_id or not prisma_client:
return None
diff --git a/litellm/proxy/_experimental/mcp_server/discoverable_endpoints.py b/litellm/proxy/_experimental/mcp_server/discoverable_endpoints.py
index ded591a8f53..8b052dd0da1 100644
--- a/litellm/proxy/_experimental/mcp_server/discoverable_endpoints.py
+++ b/litellm/proxy/_experimental/mcp_server/discoverable_endpoints.py
@@ -9,13 +9,14 @@ from litellm.llms.custom_httpx.http_handler import (
get_async_httpx_client,
httpxSpecialProvider,
)
+from litellm.proxy.auth.ip_address_utils import IPAddressUtils
from litellm.proxy.common_utils.encrypt_decrypt_utils import (
decrypt_value_helper,
encrypt_value_helper,
)
from litellm.proxy.common_utils.http_parsing_utils import _read_request_body
-from litellm.types.mcp_server.mcp_server_manager import MCPServer
from litellm.proxy.utils import get_server_root_path
+from litellm.types.mcp_server.mcp_server_manager import MCPServer
router = APIRouter(
tags=["mcp"],
@@ -300,7 +301,10 @@ async def authorize(
)
lookup_name = mcp_server_name or client_id
- mcp_server = global_mcp_server_manager.get_mcp_server_by_name(lookup_name)
+ client_ip = IPAddressUtils.get_mcp_client_ip(request)
+ mcp_server = global_mcp_server_manager.get_mcp_server_by_name(
+ lookup_name, client_ip=client_ip
+ )
if mcp_server is None:
raise HTTPException(status_code=404, detail="MCP server not found")
return await authorize_with_server(
@@ -342,7 +346,10 @@ async def token_endpoint(
)
lookup_name = mcp_server_name or client_id
- mcp_server = global_mcp_server_manager.get_mcp_server_by_name(lookup_name)
+ client_ip = IPAddressUtils.get_mcp_client_ip(request)
+ mcp_server = global_mcp_server_manager.get_mcp_server_by_name(
+ lookup_name, client_ip=client_ip
+ )
if mcp_server is None:
raise HTTPException(status_code=404, detail="MCP server not found")
return await exchange_token_with_server(
@@ -387,25 +394,60 @@ async def callback(code: str, state: str):
1. Try resource_metadata from WWW-Authenticate header (if present)
2. Fall back to path-based well-known URI: /.well-known/oauth-protected-resource/{path}
(
- If the resource identifier value contains a path or query component, any terminating slash (/)
- following the host component MUST be removed before inserting /.well-known/ and the well-known
- URI path suffix between the host component and the path(include root path) and/or query components.
+ If the resource identifier value contains a path or query component, any terminating slash (/)
+ following the host component MUST be removed before inserting /.well-known/ and the well-known
+ URI path suffix between the host component and the path(include root path) and/or query components.
https://datatracker.ietf.org/doc/html/rfc9728#section-3.1)
3. Fall back to root-based well-known URI: /.well-known/oauth-protected-resource
+
+ Dual Pattern Support:
+ - Standard MCP pattern: /mcp/{server_name} (recommended, used by mcp-inspector, VSCode Copilot)
+ - LiteLLM legacy pattern: /{server_name}/mcp (backward compatibility)
+
+ The resource URL returned matches the pattern used in the discovery request.
"""
-@router.get(f"/.well-known/oauth-protected-resource{'' if get_server_root_path() == '/' else get_server_root_path()}/{{mcp_server_name}}/mcp")
-@router.get("/.well-known/oauth-protected-resource")
-async def oauth_protected_resource_mcp(
- request: Request, mcp_server_name: Optional[str] = None
-):
+
+
+def _build_oauth_protected_resource_response(
+ request: Request,
+ mcp_server_name: Optional[str],
+ use_standard_pattern: bool,
+) -> dict:
+ """
+ Build OAuth protected resource response with the appropriate URL pattern.
+
+ Args:
+ request: FastAPI Request object
+ mcp_server_name: Name of the MCP server
+ use_standard_pattern: If True, use /mcp/{server_name} pattern;
+ if False, use /{server_name}/mcp pattern
+
+ Returns:
+ OAuth protected resource metadata dict
+ """
from litellm.proxy._experimental.mcp_server.mcp_server_manager import (
global_mcp_server_manager,
)
- # Get the correct base URL considering X-Forwarded-* headers
+
request_base_url = get_request_base_url(request)
mcp_server: Optional[MCPServer] = None
if mcp_server_name:
- mcp_server = global_mcp_server_manager.get_mcp_server_by_name(mcp_server_name)
+ client_ip = IPAddressUtils.get_mcp_client_ip(request)
+ mcp_server = global_mcp_server_manager.get_mcp_server_by_name(
+ mcp_server_name, client_ip=client_ip
+ )
+
+ # Build resource URL based on the pattern
+ if mcp_server_name:
+ if use_standard_pattern:
+ # Standard MCP pattern: /mcp/{server_name}
+ resource_url = f"{request_base_url}/mcp/{mcp_server_name}"
+ else:
+ # LiteLLM legacy pattern: /{server_name}/mcp
+ resource_url = f"{request_base_url}/{mcp_server_name}/mcp"
+ else:
+ resource_url = f"{request_base_url}/mcp"
+
return {
"authorization_servers": [
(
@@ -414,14 +456,55 @@ async def oauth_protected_resource_mcp(
else f"{request_base_url}"
)
],
- "resource": (
- f"{request_base_url}/{mcp_server_name}/mcp"
- if mcp_server_name
- else f"{request_base_url}/mcp"
- ), # this is what Claude will call
+ "resource": resource_url,
"scopes_supported": mcp_server.scopes if mcp_server else [],
}
+
+# Standard MCP pattern: /.well-known/oauth-protected-resource/mcp/{server_name}
+# This is the pattern expected by standard MCP clients (mcp-inspector, VSCode Copilot)
+@router.get(f"/.well-known/oauth-protected-resource{'' if get_server_root_path() == '/' else get_server_root_path()}/mcp/{{mcp_server_name}}")
+async def oauth_protected_resource_mcp_standard(
+ request: Request, mcp_server_name: str
+):
+ """
+ OAuth protected resource discovery endpoint using standard MCP URL pattern.
+
+ Standard pattern: /mcp/{server_name}
+ Discovery path: /.well-known/oauth-protected-resource/mcp/{server_name}
+
+ This endpoint is compliant with MCP specification and works with standard
+ MCP clients like mcp-inspector and VSCode Copilot.
+ """
+ return _build_oauth_protected_resource_response(
+ request=request,
+ mcp_server_name=mcp_server_name,
+ use_standard_pattern=True,
+ )
+
+
+# LiteLLM legacy pattern: /.well-known/oauth-protected-resource/{server_name}/mcp
+# Kept for backward compatibility with existing deployments
+@router.get(f"/.well-known/oauth-protected-resource{'' if get_server_root_path() == '/' else get_server_root_path()}/{{mcp_server_name}}/mcp")
+@router.get("/.well-known/oauth-protected-resource")
+async def oauth_protected_resource_mcp(
+ request: Request, mcp_server_name: Optional[str] = None
+):
+ """
+ OAuth protected resource discovery endpoint using LiteLLM legacy URL pattern.
+
+ Legacy pattern: /{server_name}/mcp
+ Discovery path: /.well-known/oauth-protected-resource/{server_name}/mcp
+
+ This endpoint is kept for backward compatibility. New integrations should
+ use the standard MCP pattern (/mcp/{server_name}) instead.
+ """
+ return _build_oauth_protected_resource_response(
+ request=request,
+ mcp_server_name=mcp_server_name,
+ use_standard_pattern=False,
+ )
+
"""
https://datatracker.ietf.org/doc/html/rfc8414#section-3.1
RFC 8414: Path-aware OAuth discovery
@@ -430,15 +513,26 @@ async def oauth_protected_resource_mcp(
the well-known URI suffix between the host component and the path(include root path)
component.
"""
-@router.get(f"/.well-known/oauth-authorization-server{'' if get_server_root_path() == '/' else get_server_root_path()}/{{mcp_server_name}}")
-@router.get("/.well-known/oauth-authorization-server")
-async def oauth_authorization_server_mcp(
- request: Request, mcp_server_name: Optional[str] = None
-):
+
+
+def _build_oauth_authorization_server_response(
+ request: Request,
+ mcp_server_name: Optional[str],
+) -> dict:
+ """
+ Build OAuth authorization server metadata response.
+
+ Args:
+ request: FastAPI Request object
+ mcp_server_name: Name of the MCP server
+
+ Returns:
+ OAuth authorization server metadata dict
+ """
from litellm.proxy._experimental.mcp_server.mcp_server_manager import (
global_mcp_server_manager,
)
- # Get the correct base URL considering X-Forwarded-* headers
+
request_base_url = get_request_base_url(request)
authorization_endpoint = (
@@ -454,7 +548,10 @@ async def oauth_authorization_server_mcp(
mcp_server: Optional[MCPServer] = None
if mcp_server_name:
- mcp_server = global_mcp_server_manager.get_mcp_server_by_name(mcp_server_name)
+ client_ip = IPAddressUtils.get_mcp_client_ip(request)
+ mcp_server = global_mcp_server_manager.get_mcp_server_by_name(
+ mcp_server_name, client_ip=client_ip
+ )
return {
"issuer": request_base_url, # point to your proxy
@@ -470,18 +567,58 @@ async def oauth_authorization_server_mcp(
}
+# Standard MCP pattern: /.well-known/oauth-authorization-server/mcp/{server_name}
+@router.get(f"/.well-known/oauth-authorization-server{'' if get_server_root_path() == '/' else get_server_root_path()}/mcp/{{mcp_server_name}}")
+async def oauth_authorization_server_mcp_standard(
+ request: Request, mcp_server_name: str
+):
+ """
+ OAuth authorization server discovery endpoint using standard MCP URL pattern.
+
+ Standard pattern: /mcp/{server_name}
+ Discovery path: /.well-known/oauth-authorization-server/mcp/{server_name}
+ """
+ return _build_oauth_authorization_server_response(
+ request=request,
+ mcp_server_name=mcp_server_name,
+ )
+
+
+# LiteLLM legacy pattern and root endpoint
+@router.get(f"/.well-known/oauth-authorization-server{'' if get_server_root_path() == '/' else get_server_root_path()}/{{mcp_server_name}}")
+@router.get("/.well-known/oauth-authorization-server")
+async def oauth_authorization_server_mcp(
+ request: Request, mcp_server_name: Optional[str] = None
+):
+ """
+ OAuth authorization server discovery endpoint.
+
+ Supports both legacy pattern (/{server_name}) and root endpoint.
+ """
+ return _build_oauth_authorization_server_response(
+ request=request,
+ mcp_server_name=mcp_server_name,
+ )
+
+
# Alias for standard OpenID discovery
@router.get("/.well-known/openid-configuration")
async def openid_configuration(request: Request):
return await oauth_authorization_server_mcp(request)
+# Additional legacy pattern support
@router.get("/.well-known/oauth-authorization-server/{mcp_server_name}/mcp")
-@router.get("/.well-known/oauth-authorization-server")
-async def oauth_authorization_server_root(
- request: Request, mcp_server_name: Optional[str] = None
+async def oauth_authorization_server_legacy(
+ request: Request, mcp_server_name: str
):
- return await oauth_authorization_server_mcp(request, mcp_server_name)
+ """
+ OAuth authorization server discovery for legacy /{server_name}/mcp pattern.
+ """
+ return _build_oauth_authorization_server_response(
+ request=request,
+ mcp_server_name=mcp_server_name,
+ )
@router.post("/{mcp_server_name}/register")
@@ -505,7 +642,10 @@ async def register_client(request: Request, mcp_server_name: Optional[str] = Non
if not mcp_server_name:
return dummy_return
- mcp_server = global_mcp_server_manager.get_mcp_server_by_name(mcp_server_name)
+ client_ip = IPAddressUtils.get_mcp_client_ip(request)
+ mcp_server = global_mcp_server_manager.get_mcp_server_by_name(
+ mcp_server_name, client_ip=client_ip
+ )
if mcp_server is None:
return dummy_return
return await register_client_with_server(
diff --git a/litellm/proxy/_experimental/mcp_server/guardrail_translation/handler.py b/litellm/proxy/_experimental/mcp_server/guardrail_translation/handler.py
index 8d6d236b884..14bbb82808d 100644
--- a/litellm/proxy/_experimental/mcp_server/guardrail_translation/handler.py
+++ b/litellm/proxy/_experimental/mcp_server/guardrail_translation/handler.py
@@ -1,26 +1,37 @@
"""
MCP Guardrail Handler for Unified Guardrails.
-This handler works with the synthetic "messages" payload generated by
-`ProxyLogging._convert_mcp_to_llm_format`, which always produces a single user
-message whose `content` string encodes the MCP tool name and arguments. The
-handler simply feeds that text through the configured guardrail and writes the
-result back onto the message.
+Converts an MCP call_tool (name + arguments) into a single OpenAI-compatible
+tool_call and passes it to apply_guardrail. Works with the synthetic payload
+from ProxyLogging._convert_mcp_to_llm_format.
+
+Note: For MCP tool definitions (schema) -> OpenAI tools=[], see
+litellm.experimental_mcp_client.tools.transform_mcp_tool_to_openai_tool
+when you have a full MCP Tool from list_tools. Here we only have the call
+payload (name + arguments) so we just build the tool_call.
"""
from typing import TYPE_CHECKING, Any, Dict, Optional
+from mcp.types import Tool as MCPTool
+
from litellm._logging import verbose_proxy_logger
+from litellm.experimental_mcp_client.tools import transform_mcp_tool_to_openai_tool
from litellm.llms.base_llm.guardrail_translation.base_translation import BaseTranslation
+from litellm.types.llms.openai import (
+ ChatCompletionToolParam,
+ ChatCompletionToolParamFunctionChunk,
+)
from litellm.types.utils import GenericGuardrailAPIInputs
if TYPE_CHECKING:
- from litellm.integrations.custom_guardrail import CustomGuardrail
from mcp.types import CallToolResult
+ from litellm.integrations.custom_guardrail import CustomGuardrail
+
class MCPGuardrailTranslationHandler(BaseTranslation):
- """Guardrail translation handler for MCP tool calls."""
+ """Guardrail translation handler for MCP tool calls (passes a single tool_call to guardrail)."""
async def process_input_messages(
self,
@@ -28,51 +39,51 @@ class MCPGuardrailTranslationHandler(BaseTranslation):
guardrail_to_apply: "CustomGuardrail",
litellm_logging_obj: Optional[Any] = None,
) -> Dict[str, Any]:
- messages = data.get("messages")
- if not isinstance(messages, list) or not messages:
- verbose_proxy_logger.debug("MCP Guardrail: No messages to process")
+ mcp_tool_name = data.get("mcp_tool_name") or data.get("name")
+ mcp_arguments = data.get("mcp_arguments") or data.get("arguments")
+ mcp_tool_description = data.get("mcp_tool_description") or data.get(
+ "description"
+ )
+ if mcp_arguments is None or not isinstance(mcp_arguments, dict):
+ mcp_arguments = {}
+
+ if not mcp_tool_name:
+ verbose_proxy_logger.debug("MCP Guardrail: mcp_tool_name missing")
return data
- first_message = messages[0]
- content: Optional[str] = None
- if isinstance(first_message, dict):
- content = first_message.get("content")
- else:
- content = getattr(first_message, "content", None)
+ # Convert MCP input via transform_mcp_tool_to_openai_tool, then map to litellm
+ # ChatCompletionToolParam (openai SDK type has incompatible strict/cache_control).
+ mcp_tool = MCPTool(
+ name=mcp_tool_name,
+ description=mcp_tool_description or "",
+ inputSchema={}, # Call payload has no schema; guardrail gets args from request_data
+ )
+ openai_tool = transform_mcp_tool_to_openai_tool(mcp_tool)
+ fn = openai_tool["function"]
+ tool_def: ChatCompletionToolParam = {
+ "type": "function",
+ "function": ChatCompletionToolParamFunctionChunk(
+ name=fn["name"],
+ description=fn.get("description") or "",
+ parameters=fn.get("parameters")
+ or {
+ "type": "object",
+ "properties": {},
+ "additionalProperties": False,
+ },
+ strict=fn.get("strict", False) or False, # Default to False if None
+ ),
+ }
+ inputs: GenericGuardrailAPIInputs = GenericGuardrailAPIInputs(
+ tools=[tool_def],
+ )
- if not isinstance(content, str):
- verbose_proxy_logger.debug(
- "MCP Guardrail: Message content missing or not a string",
- )
- return data
-
- guardrailed_inputs = await guardrail_to_apply.apply_guardrail(
- inputs=GenericGuardrailAPIInputs(texts=[content]),
+ await guardrail_to_apply.apply_guardrail(
+ inputs=inputs,
request_data=data,
input_type="request",
logging_obj=litellm_logging_obj,
)
- guardrailed_texts = (
- guardrailed_inputs.get("texts", []) if guardrailed_inputs else []
- )
-
- if guardrailed_texts:
- new_content = guardrailed_texts[0]
- if isinstance(first_message, dict):
- first_message["content"] = new_content
- else:
- setattr(first_message, "content", new_content)
-
- verbose_proxy_logger.debug(
- "MCP Guardrail: Updated content for tool %s",
- data.get("mcp_tool_name"),
- )
- else:
- verbose_proxy_logger.debug(
- "MCP Guardrail: Guardrail returned no text updates for tool %s",
- data.get("mcp_tool_name"),
- )
-
return data
async def process_output_response(
@@ -82,7 +93,6 @@ class MCPGuardrailTranslationHandler(BaseTranslation):
litellm_logging_obj: Optional[Any] = None,
user_api_key_dict: Optional[Any] = None,
) -> Any:
- # Not implemented: MCP guardrail translation never calls this path today.
verbose_proxy_logger.debug(
"MCP Guardrail: Output processing not implemented for MCP tools",
)
diff --git a/litellm/proxy/_experimental/mcp_server/mcp_server_manager.py b/litellm/proxy/_experimental/mcp_server/mcp_server_manager.py
index 53dc6e512c5..e7174f943b2 100644
--- a/litellm/proxy/_experimental/mcp_server/mcp_server_manager.py
+++ b/litellm/proxy/_experimental/mcp_server/mcp_server_manager.py
@@ -11,7 +11,7 @@ import datetime
import hashlib
import json
import re
-from typing import Any, Dict, List, Literal, Optional, Set, Tuple, Union, cast
+from typing import Any, Callable, Dict, List, Literal, Optional, Set, Tuple, Union, cast
from urllib.parse import urlparse
from fastapi import HTTPException
@@ -30,7 +30,6 @@ from pydantic import AnyUrl
import litellm
from litellm._logging import verbose_logger
-from litellm.types.utils import CallTypes
from litellm.exceptions import BlockedPiiEntityError, GuardrailRaisedException
from litellm.experimental_mcp_client.client import MCPClient
from litellm.llms.custom_httpx.http_handler import get_async_httpx_client
@@ -42,6 +41,7 @@ from litellm.proxy._experimental.mcp_server.utils import (
add_server_prefix_to_name,
get_server_prefix,
is_tool_name_prefixed,
+ merge_mcp_headers,
normalize_server_name,
split_server_prefix_from_name,
validate_mcp_server_name,
@@ -53,6 +53,7 @@ from litellm.proxy._types import (
MCPTransportType,
UserAPIKeyAuth,
)
+from litellm.proxy.auth.ip_address_utils import IPAddressUtils
from litellm.proxy.common_utils.encrypt_decrypt_utils import decrypt_value_helper
from litellm.proxy.utils import ProxyLogging
from litellm.types.llms.custom_http import httpxSpecialProvider
@@ -62,7 +63,26 @@ from litellm.types.mcp_server.mcp_server_manager import (
MCPOAuthMetadata,
MCPServer,
)
-from mcp.shared.tool_name_validation import SEP_986_URL, validate_tool_name
+from litellm.types.utils import CallTypes
+
+try:
+ from mcp.shared.tool_name_validation import (
+ validate_tool_name, # pyright: ignore[reportAssignmentType]
+ )
+ from mcp.shared.tool_name_validation import (
+ SEP_986_URL,
+ )
+except ImportError:
+ from pydantic import BaseModel
+
+ SEP_986_URL = "https://github.com/modelcontextprotocol/protocol/blob/main/proposals/0001-tool-name-validation.md"
+
+ class _ToolNameValidationResult(BaseModel):
+ is_valid: bool = True
+ warnings: list = []
+
+ def validate_tool_name(name: str) -> _ToolNameValidationResult: # type: ignore[misc]
+ return _ToolNameValidationResult()
# Probe includes characters on both sides of the separator to mimic real prefixed tool names.
@@ -89,7 +109,9 @@ def _warn_on_server_name_fields(
if result.is_valid:
return
- warning_text = "; ".join(result.warnings) if result.warnings else "Validation failed"
+ warning_text = (
+ "; ".join(result.warnings) if result.warnings else "Validation failed"
+ )
verbose_logger.warning(
"MCP server '%s' has invalid %s '%s': %s",
server_id,
@@ -102,7 +124,6 @@ def _warn_on_server_name_fields(
_warn("server_name", server_name)
-
def _deserialize_json_dict(data: Any) -> Optional[Dict[str, str]]:
"""
Deserialize optional JSON mappings stored in the database.
@@ -307,6 +328,9 @@ class MCPServerManager:
access_groups=server_config.get("access_groups", None),
static_headers=server_config.get("static_headers", None),
allow_all_keys=bool(server_config.get("allow_all_keys", False)),
+ available_on_public_internet=bool(
+ server_config.get("available_on_public_internet", False)
+ ),
)
self.config_mcp_servers[server_id] = new_server
@@ -372,7 +396,7 @@ class MCPServerManager:
server_prefix = get_server_prefix(server)
# Build headers from server configuration
- headers = {}
+ headers: Dict[str, str] = {}
# Add authentication headers if configured
if server.authentication_token:
@@ -385,10 +409,18 @@ class MCPServerManager:
elif server.auth_type == MCPAuth.basic:
headers["Authorization"] = f"Basic {server.authentication_token}"
- # Add any extra headers from server config
- # Note: extra_headers is a List[str] of header names to forward, not a dict
- # For OpenAPI tools, we'll just use the authentication headers
- # If extra_headers were needed, they would be processed separately
+ # Add any static headers from server config.
+ #
+ # Note: `extra_headers` on MCPServer is a List[str] of header names to forward
+ # from the client request (not available in this OpenAPI tool generation step).
+ # `static_headers` is a dict of concrete headers to always send.
+ headers = (
+ merge_mcp_headers(
+ extra_headers=headers,
+ static_headers=server.static_headers,
+ )
+ or {}
+ )
verbose_logger.debug(
f"Using headers for OpenAPI tools (excluding sensitive values): "
@@ -444,12 +476,12 @@ class MCPServerManager:
)
# Update tool name to server name mapping (for both prefixed and base names)
- self.tool_name_to_mcp_server_name_mapping[
- base_tool_name
- ] = server_prefix
- self.tool_name_to_mcp_server_name_mapping[
- prefixed_tool_name
- ] = server_prefix
+ self.tool_name_to_mcp_server_name_mapping[base_tool_name] = (
+ server_prefix
+ )
+ self.tool_name_to_mcp_server_name_mapping[prefixed_tool_name] = (
+ server_prefix
+ )
registered_count += 1
verbose_logger.debug(
@@ -597,6 +629,9 @@ class MCPServerManager:
allowed_tools=getattr(mcp_server, "allowed_tools", None),
disallowed_tools=getattr(mcp_server, "disallowed_tools", None),
allow_all_keys=mcp_server.allow_all_keys,
+ available_on_public_internet=bool(
+ getattr(mcp_server, "available_on_public_internet", False)
+ ),
updated_at=getattr(mcp_server, "updated_at", None),
)
return new_server
@@ -671,6 +706,23 @@ class MCPServerManager:
verbose_logger.warning(f"Failed to get allowed MCP servers: {str(e)}.")
return allow_all_server_ids
+ def filter_server_ids_by_ip(
+ self, server_ids: List[str], client_ip: Optional[str]
+ ) -> List[str]:
+ """
+ Filter server IDs by client IP — external callers only see public servers.
+
+ Returns server_ids unchanged when client_ip is None (no filtering).
+ """
+ if client_ip is None:
+ return server_ids
+ return [
+ sid
+ for sid in server_ids
+ if (s := self.get_mcp_server_by_id(sid)) is not None
+ and self._is_server_accessible_from_ip(s, client_ip)
+ ]
+
async def get_tools_for_server(self, server_id: str) -> List[MCPTool]:
"""
Get the tools for a given server
@@ -1819,6 +1871,7 @@ class MCPServerManager:
oauth2_headers: Optional[Dict[str, str]],
raw_headers: Optional[Dict[str, str]],
proxy_logging_obj: Optional[ProxyLogging],
+ host_progress_callback: Optional[Callable] = None,
) -> CallToolResult:
"""
Call a regular MCP tool using the MCP client.
@@ -1903,7 +1956,9 @@ class MCPServerManager:
)
async def _call_tool_via_client(client, params):
- return await client.call_tool(params)
+ return await client.call_tool(
+ params, host_progress_callback=host_progress_callback
+ )
tasks.append(
asyncio.create_task(_call_tool_via_client(client, call_tool_params))
@@ -1940,6 +1995,7 @@ class MCPServerManager:
proxy_logging_obj: Optional[ProxyLogging] = None,
oauth2_headers: Optional[Dict[str, str]] = None,
raw_headers: Optional[Dict[str, str]] = None,
+ host_progress_callback: Optional[Callable] = None,
) -> CallToolResult:
"""
Call a tool with the given name and arguments
@@ -2015,6 +2071,7 @@ class MCPServerManager:
oauth2_headers=oauth2_headers,
raw_headers=raw_headers,
proxy_logging_obj=proxy_logging_obj,
+ host_progress_callback=host_progress_callback,
)
# For OpenAPI tools, await outside the client context
@@ -2171,6 +2228,42 @@ class MCPServerManager:
servers.append(server)
return servers
+ def _get_general_settings(self) -> Dict[str, Any]:
+ """Get general_settings, importing lazily to avoid circular imports."""
+ try:
+ from litellm.proxy.proxy_server import (
+ general_settings as proxy_general_settings,
+ )
+ return proxy_general_settings
+ except ImportError:
+ # Fallback if proxy_server not available
+ return {}
+
+ def _is_server_accessible_from_ip(
+ self, server: MCPServer, client_ip: Optional[str]
+ ) -> bool:
+ """
+ Check if a server is accessible from the given client IP.
+
+ - If client_ip is None, no IP filtering is applied (internal callers).
+ - If the server has available_on_public_internet=True, it's always accessible.
+ - Otherwise, only internal/private IPs can access it.
+ """
+ if client_ip is None:
+ return True
+ if server.available_on_public_internet:
+ return True
+ # Check backwards compat: litellm.public_mcp_servers
+ public_ids = set(litellm.public_mcp_servers or [])
+ if server.server_id in public_ids:
+ return True
+ # Non-public server: only accessible from internal IPs
+ general_settings = self._get_general_settings()
+ internal_networks = IPAddressUtils.parse_internal_networks(
+ general_settings.get("mcp_internal_ip_ranges")
+ )
+ return IPAddressUtils.is_internal_ip(client_ip, internal_networks)
+
def get_mcp_server_by_id(self, server_id: str) -> Optional[MCPServer]:
"""
Get the MCP Server from the server id
@@ -2183,27 +2276,72 @@ class MCPServerManager:
def get_public_mcp_servers(self) -> List[MCPServer]:
"""
- Get the public MCP servers
+ Get the public MCP servers (available_on_public_internet=True flag on server).
+ Also includes servers from litellm.public_mcp_servers for backwards compat.
"""
servers: List[MCPServer] = []
- if litellm.public_mcp_servers is None:
- return servers
- for server_id in litellm.public_mcp_servers:
- server = self.get_mcp_server_by_id(server_id)
- if server:
+ public_ids = set(litellm.public_mcp_servers or [])
+ for server in self.get_registry().values():
+ if server.available_on_public_internet or server.server_id in public_ids:
servers.append(server)
return servers
- def get_mcp_server_by_name(self, server_name: str) -> Optional[MCPServer]:
+ def get_mcp_server_by_name(
+ self, server_name: str, client_ip: Optional[str] = None
+ ) -> Optional[MCPServer]:
"""
- Get the MCP Server from the server name
+ Get the MCP Server from the server name.
+
+ Uses priority-based matching to avoid collisions:
+ 1. First pass: exact alias match (highest priority)
+ 2. Second pass: exact server_name match
+ 3. Third pass: exact name match (lowest priority)
+
+ Args:
+ server_name: The server name to look up.
+ client_ip: Optional client IP for access control. When provided,
+ non-public servers are hidden from external IPs.
"""
registry = self.get_registry()
+ # Pass 1: Match by alias (highest priority)
+ for server in registry.values():
+ if server.alias == server_name:
+ if not self._is_server_accessible_from_ip(server, client_ip):
+ return None
+ return server
+ # Pass 2: Match by server_name
for server in registry.values():
if server.server_name == server_name:
+ if not self._is_server_accessible_from_ip(server, client_ip):
+ return None
+ return server
+ # Pass 3: Match by name (lowest priority)
+ for server in registry.values():
+ if server.name == server_name:
+ if not self._is_server_accessible_from_ip(server, client_ip):
+ return None
return server
return None
+ def get_filtered_registry(
+ self, client_ip: Optional[str] = None
+ ) -> Dict[str, MCPServer]:
+ """
+ Get registry filtered by client IP access control.
+
+ Args:
+ client_ip: Optional client IP. When provided, non-public servers
+ are hidden from external IPs. When None, returns all servers.
+ """
+ registry = self.get_registry()
+ if client_ip is None:
+ return registry
+ return {
+ k: v
+ for k, v in registry.items()
+ if self._is_server_accessible_from_ip(v, client_ip)
+ }
+
def _generate_stable_server_id(
self,
server_name: str,
@@ -2433,6 +2571,7 @@ class MCPServerManager:
token_url=server.token_url,
registration_url=server.registration_url,
allow_all_keys=server.allow_all_keys,
+ available_on_public_internet=server.available_on_public_internet,
)
async def get_all_mcp_servers_unfiltered(self) -> List[LiteLLM_MCPServerTable]:
diff --git a/litellm/proxy/_experimental/mcp_server/rest_endpoints.py b/litellm/proxy/_experimental/mcp_server/rest_endpoints.py
index 48f7a8b0b7b..2fe40bb197e 100644
--- a/litellm/proxy/_experimental/mcp_server/rest_endpoints.py
+++ b/litellm/proxy/_experimental/mcp_server/rest_endpoints.py
@@ -8,9 +8,12 @@ from litellm._logging import verbose_logger
from litellm.proxy._experimental.mcp_server.ui_session_utils import (
build_effective_auth_contexts,
)
+from litellm.proxy._experimental.mcp_server.utils import merge_mcp_headers
from litellm.proxy._types import UserAPIKeyAuth
+from litellm.proxy.auth.ip_address_utils import IPAddressUtils
from litellm.proxy.auth.user_api_key_auth import user_api_key_auth
from litellm.types.mcp import MCPAuth
+from litellm.types.utils import CallTypes
MCP_AVAILABLE: bool = True
try:
@@ -27,6 +30,7 @@ router = APIRouter(
if MCP_AVAILABLE:
from mcp.types import Tool as MCPTool
+
from litellm.proxy._experimental.mcp_server.mcp_server_manager import (
global_mcp_server_manager,
)
@@ -75,6 +79,82 @@ if MCP_AVAILABLE:
for tool in tools
]
+ def _extract_mcp_headers_from_request(
+ request: Request,
+ mcp_request_handler_cls,
+ ) -> tuple:
+ """
+ Extract MCP auth headers from HTTP request.
+
+ Returns:
+ Tuple of (mcp_auth_header, mcp_server_auth_headers, raw_headers)
+ """
+ headers = request.headers
+ raw_headers = dict(headers)
+ mcp_auth_header = mcp_request_handler_cls._get_mcp_auth_header_from_headers(
+ headers
+ )
+ mcp_server_auth_headers = (
+ mcp_request_handler_cls._get_mcp_server_auth_headers_from_headers(headers)
+ )
+ return mcp_auth_header, mcp_server_auth_headers, raw_headers
+
+ async def _resolve_allowed_mcp_servers_with_ip_filter(
+ request: Request,
+ user_api_key_dict: UserAPIKeyAuth,
+ server_id: str,
+ ) -> List[MCPServer]:
+ """
+ Resolve allowed MCP servers for a tool call with IP filtering.
+
+ Args:
+ request: The HTTP request object
+ user_api_key_dict: The user's API key auth object
+ server_id: The server ID to validate access for
+
+ Returns:
+ List of allowed MCPServer objects
+
+ Raises:
+ HTTPException: If the server_id is not allowed
+ """
+ # Get all auth contexts
+ auth_contexts = await build_effective_auth_contexts(user_api_key_dict)
+
+ # Collect allowed server IDs from all contexts, then apply IP filtering
+ _rest_client_ip = IPAddressUtils.get_mcp_client_ip(request)
+ allowed_server_ids_set = set()
+ for auth_context in auth_contexts:
+ servers = await global_mcp_server_manager.get_allowed_mcp_servers(
+ user_api_key_auth=auth_context,
+ )
+ allowed_server_ids_set.update(servers)
+
+ allowed_server_ids_set = set(
+ global_mcp_server_manager.filter_server_ids_by_ip(
+ list(allowed_server_ids_set), _rest_client_ip
+ )
+ )
+
+ # Check if the specified server_id is allowed
+ if server_id not in allowed_server_ids_set:
+ raise HTTPException(
+ status_code=403,
+ detail={
+ "error": "access_denied",
+ "message": f"The key is not allowed to access server {server_id}",
+ },
+ )
+
+ # Build allowed_mcp_servers list (only include allowed servers)
+ allowed_mcp_servers: List[MCPServer] = []
+ for allowed_server_id in allowed_server_ids_set:
+ server = global_mcp_server_manager.get_mcp_server_by_id(allowed_server_id)
+ if server is not None:
+ allowed_mcp_servers.append(server)
+
+ return allowed_mcp_servers
+
async def _get_tools_for_single_server(
server,
server_auth_header,
@@ -95,6 +175,35 @@ if MCP_AVAILABLE:
return _create_tool_response_objects(tools, server.mcp_info)
+ async def _resolve_allowed_mcp_servers_for_tool_call(
+ user_api_key_dict: UserAPIKeyAuth,
+ server_id: str,
+ ) -> List[MCPServer]:
+ """Resolve allowed MCP servers for the given user and validate server_id access."""
+ auth_contexts = await build_effective_auth_contexts(user_api_key_dict)
+ allowed_server_ids_set = set()
+ for auth_context in auth_contexts:
+ servers = await global_mcp_server_manager.get_allowed_mcp_servers(
+ user_api_key_auth=auth_context
+ )
+ allowed_server_ids_set.update(servers)
+ if server_id not in allowed_server_ids_set:
+ raise HTTPException(
+ status_code=403,
+ detail={
+ "error": "access_denied",
+ "message": f"The key is not allowed to access server {server_id}",
+ },
+ )
+ allowed_mcp_servers: List[MCPServer] = []
+ for allowed_server_id in allowed_server_ids_set:
+ server = global_mcp_server_manager.get_mcp_server_by_id(
+ allowed_server_id
+ )
+ if server is not None:
+ allowed_mcp_servers.append(server)
+ return allowed_mcp_servers
+
########################################################
@router.get("/tools/list", dependencies=[Depends(user_api_key_auth)])
async def list_tool_rest_api(
@@ -141,21 +250,25 @@ if MCP_AVAILABLE:
auth_contexts = await build_effective_auth_contexts(user_api_key_dict)
+ _rest_client_ip = IPAddressUtils.get_mcp_client_ip(request)
+
allowed_server_ids_set = set()
for auth_context in auth_contexts:
servers = await global_mcp_server_manager.get_allowed_mcp_servers(
- user_api_key_auth=auth_context
+ user_api_key_auth=auth_context,
)
allowed_server_ids_set.update(servers)
- allowed_server_ids = list(allowed_server_ids_set)
+ allowed_server_ids = global_mcp_server_manager.filter_server_ids_by_ip(
+ list(allowed_server_ids_set), _rest_client_ip
+ )
list_tools_result = []
error_message = None
# If server_id is specified, only query that specific server
if server_id:
- if server_id not in allowed_server_ids_set:
+ if server_id not in allowed_server_ids:
raise HTTPException(
status_code=403,
detail={
@@ -163,7 +276,9 @@ if MCP_AVAILABLE:
"message": f"The key is not allowed to access server {server_id}",
},
)
- server = global_mcp_server_manager.get_mcp_server_by_id(server_id)
+ server = global_mcp_server_manager.get_mcp_server_by_id(
+ server_id
+ )
if server is None:
return {
"tools": [],
@@ -260,7 +375,14 @@ if MCP_AVAILABLE:
from litellm.proxy._experimental.mcp_server.auth.user_api_key_auth_mcp import (
MCPRequestHandler,
)
- from litellm.proxy.proxy_server import add_litellm_data_to_request, proxy_config
+ from litellm.proxy.common_request_processing import (
+ ProxyBaseLLMRequestProcessing,
+ )
+ from litellm.proxy.proxy_server import (
+ general_settings,
+ proxy_config,
+ proxy_logging_obj,
+ )
try:
data = await request.json()
@@ -288,28 +410,22 @@ if MCP_AVAILABLE:
tool_arguments = data.get("arguments")
- data = await add_litellm_data_to_request(
- data=data,
- request=request,
- user_api_key_dict=user_api_key_dict,
- proxy_config=proxy_config,
+ proxy_base_llm_response_processor = ProxyBaseLLMRequestProcessing(data=data)
+ data, logging_obj = (
+ await proxy_base_llm_response_processor.common_processing_pre_call_logic(
+ request=request,
+ user_api_key_dict=user_api_key_dict,
+ proxy_config=proxy_config,
+ route_type=CallTypes.call_mcp_tool.value,
+ proxy_logging_obj=proxy_logging_obj,
+ general_settings=general_settings,
+ )
)
- # FIX: Extract MCP auth headers from request
- # The UI sends bearer token in x-mcp-auth header and server-specific headers,
- # but they weren't being extracted and passed to call_mcp_tool.
- # This fix ensures auth headers are properly extracted from the HTTP request
- # and passed through to the MCP server for authentication.
- headers = request.headers
- raw_headers_from_request = dict(headers)
- mcp_auth_header = MCPRequestHandler._get_mcp_auth_header_from_headers(
- headers
+ # Extract MCP auth headers from request and add to data dict
+ mcp_auth_header, mcp_server_auth_headers, raw_headers_from_request = (
+ _extract_mcp_headers_from_request(request, MCPRequestHandler)
)
- mcp_server_auth_headers = (
- MCPRequestHandler._get_mcp_server_auth_headers_from_headers(headers)
- )
-
- # Add extracted headers to data dict to pass to call_mcp_tool
if mcp_auth_header:
data["mcp_auth_header"] = mcp_auth_header
if mcp_server_auth_headers:
@@ -321,35 +437,10 @@ if MCP_AVAILABLE:
if "metadata" in data and "user_api_key_auth" in data["metadata"]:
data["user_api_key_auth"] = data["metadata"]["user_api_key_auth"]
- # Get all auth contexts
- auth_contexts = await build_effective_auth_contexts(user_api_key_dict)
-
- # Collect allowed server IDs from all contexts
- allowed_server_ids_set = set()
- for auth_context in auth_contexts:
- servers = await global_mcp_server_manager.get_allowed_mcp_servers(
- user_api_key_auth=auth_context
- )
- allowed_server_ids_set.update(servers)
-
- # Check if the specified server_id is allowed
- if server_id not in allowed_server_ids_set:
- raise HTTPException(
- status_code=403,
- detail={
- "error": "access_denied",
- "message": f"The key is not allowed to access server {server_id}",
- },
- )
-
- # Build allowed_mcp_servers list (only include allowed servers)
- allowed_mcp_servers: List[MCPServer] = []
- for allowed_server_id in allowed_server_ids_set:
- server = global_mcp_server_manager.get_mcp_server_by_id(
- allowed_server_id
- )
- if server is not None:
- allowed_mcp_servers.append(server)
+ # Resolve allowed MCP servers with IP filtering
+ allowed_mcp_servers = await _resolve_allowed_mcp_servers_with_ip_filter(
+ request, user_api_key_dict, server_id
+ )
# Call execute_mcp_tool directly (permission checks already done)
result = await execute_mcp_tool(
@@ -438,16 +529,22 @@ if MCP_AVAILABLE:
command=request.command,
args=request.args,
env=request.env,
+ static_headers=request.static_headers,
)
stdio_env = global_mcp_server_manager._build_stdio_env(
server_model, raw_headers
)
+ merged_headers = merge_mcp_headers(
+ extra_headers=oauth2_headers,
+ static_headers=request.static_headers,
+ )
+
client = global_mcp_server_manager._create_mcp_client(
server=server_model,
mcp_auth_header=mcp_auth_header,
- extra_headers=oauth2_headers,
+ extra_headers=merged_headers,
stdio_env=stdio_env,
)
diff --git a/litellm/proxy/_experimental/mcp_server/semantic_tool_filter.py b/litellm/proxy/_experimental/mcp_server/semantic_tool_filter.py
new file mode 100644
index 00000000000..e5cb6a0098d
--- /dev/null
+++ b/litellm/proxy/_experimental/mcp_server/semantic_tool_filter.py
@@ -0,0 +1,250 @@
+"""
+Semantic MCP Tool Filtering using semantic-router
+
+Filters MCP tools semantically for /chat/completions and /responses endpoints.
+"""
+from typing import TYPE_CHECKING, Any, Dict, List, Optional
+
+from litellm._logging import verbose_logger
+
+if TYPE_CHECKING:
+ from semantic_router.routers import SemanticRouter
+
+ from litellm.router import Router
+
+
+class SemanticMCPToolFilter:
+ """Filters MCP tools using semantic similarity to reduce context window size."""
+
+ def __init__(
+ self,
+ embedding_model: str,
+ litellm_router_instance: "Router",
+ top_k: int = 10,
+ similarity_threshold: float = 0.3,
+ enabled: bool = True,
+ ):
+ """
+ Initialize the semantic tool filter.
+
+ Args:
+ embedding_model: Model to use for embeddings (e.g., "text-embedding-3-small")
+ litellm_router_instance: Router instance for embedding generation
+ top_k: Maximum number of tools to return
+ similarity_threshold: Minimum similarity score for filtering
+ enabled: Whether filtering is enabled
+ """
+ self.enabled = enabled
+ self.top_k = top_k
+ self.similarity_threshold = similarity_threshold
+ self.embedding_model = embedding_model
+ self.router_instance = litellm_router_instance
+ self.tool_router: Optional["SemanticRouter"] = None
+ self._tool_map: Dict[str, Any] = {} # MCPTool objects or OpenAI function dicts
+
+ async def build_router_from_mcp_registry(self) -> None:
+ """Build semantic router from all MCP tools in the registry (no auth checks)."""
+ from litellm.proxy._experimental.mcp_server.mcp_server_manager import (
+ global_mcp_server_manager,
+ )
+
+ try:
+ # Get all servers from registry without auth checks
+ registry = global_mcp_server_manager.get_registry()
+ if not registry:
+ verbose_logger.warning("MCP registry is empty")
+ self.tool_router = None
+ return
+
+ # Fetch tools from all servers in parallel
+ all_tools = []
+ for server_id, server in registry.items():
+ try:
+ tools = await global_mcp_server_manager.get_tools_for_server(server_id)
+ all_tools.extend(tools)
+ except Exception as e:
+ verbose_logger.warning(f"Failed to fetch tools from server {server_id}: {e}")
+ continue
+
+ if not all_tools:
+ verbose_logger.warning("No MCP tools found in registry")
+ self.tool_router = None
+ return
+
+ verbose_logger.info(f"Fetched {len(all_tools)} tools from {len(registry)} MCP servers")
+ self._build_router(all_tools)
+
+ except Exception as e:
+ verbose_logger.error(f"Failed to build router from MCP registry: {e}")
+ self.tool_router = None
+ raise
+
+ def _extract_tool_info(self, tool) -> tuple[str, str]:
+ """Extract name and description from MCP tool or OpenAI function dict."""
+ name: str
+ description: str
+
+ if isinstance(tool, dict):
+ # OpenAI function format
+ name = tool.get("name", "")
+ description = tool.get("description", name)
+ else:
+ # MCPTool object
+ name = str(tool.name)
+ description = str(tool.description) if tool.description else str(tool.name)
+
+ return name, description
+
+ def _build_router(self, tools: List) -> None:
+ """Build semantic router with tools (MCPTool objects or OpenAI function dicts)."""
+ from semantic_router.routers import SemanticRouter
+ from semantic_router.routers.base import Route
+
+ from litellm.router_strategy.auto_router.litellm_encoder import (
+ LiteLLMRouterEncoder,
+ )
+
+ if not tools:
+ self.tool_router = None
+ return
+
+ try:
+ # Convert tools to routes
+ routes = []
+ self._tool_map = {}
+
+ for tool in tools:
+ name, description = self._extract_tool_info(tool)
+ self._tool_map[name] = tool
+
+ routes.append(
+ Route(
+ name=name,
+ description=description,
+ utterances=[description],
+ score_threshold=self.similarity_threshold,
+ )
+ )
+
+ self.tool_router = SemanticRouter(
+ routes=routes,
+ encoder=LiteLLMRouterEncoder(
+ litellm_router_instance=self.router_instance,
+ model_name=self.embedding_model,
+ score_threshold=self.similarity_threshold,
+ ),
+ auto_sync="local",
+ )
+
+ verbose_logger.info(
+ f"Built semantic router with {len(routes)} tools"
+ )
+
+ except Exception as e:
+ verbose_logger.error(f"Failed to build semantic router: {e}")
+ self.tool_router = None
+ raise
+
+ async def filter_tools(
+ self,
+ query: str,
+ available_tools: List[Any],
+ top_k: Optional[int] = None,
+ ) -> List[Any]:
+ """
+ Filter tools semantically based on query.
+
+ Args:
+ query: User query to match against tools
+ available_tools: Full list of available MCP tools
+ top_k: Override default top_k (optional)
+
+ Returns:
+ Filtered and ordered list of tools (up to top_k)
+ """
+ # Early returns for cases where we can't/shouldn't filter
+ if not self.enabled:
+ return available_tools
+
+ if not available_tools:
+ return available_tools
+
+ if not query or not query.strip():
+ return available_tools
+
+ # Router should be built on startup - if not, something went wrong
+ if self.tool_router is None:
+ verbose_logger.warning("Router not initialized - was build_router_from_mcp_registry() called on startup?")
+ return available_tools
+
+ # Run semantic filtering
+ try:
+ limit = top_k or self.top_k
+ matches = self.tool_router(text=query, limit=limit)
+ matched_tool_names = self._extract_tool_names_from_matches(matches)
+
+ if not matched_tool_names:
+ return available_tools
+
+ return self._get_tools_by_names(matched_tool_names, available_tools)
+
+ except Exception as e:
+ verbose_logger.error(f"Semantic tool filter failed: {e}", exc_info=True)
+ return available_tools
+
+ def _extract_tool_names_from_matches(self, matches) -> List[str]:
+ """Extract tool names from semantic router match results."""
+ if not matches:
+ return []
+
+ # Handle single match
+ if hasattr(matches, "name") and matches.name:
+ return [matches.name]
+
+ # Handle list of matches
+ if isinstance(matches, list):
+ return [m.name for m in matches if hasattr(m, "name") and m.name]
+
+ return []
+
+ def _get_tools_by_names(
+ self, tool_names: List[str], available_tools: List[Any]
+ ) -> List[Any]:
+ """Get tools from available_tools by their names, preserving order."""
+ # Match tools from available_tools (preserves format - dict or MCPTool)
+ matched_tools = []
+ for tool in available_tools:
+ tool_name, _ = self._extract_tool_info(tool)
+ if tool_name in tool_names:
+ matched_tools.append(tool)
+
+ # Reorder to match semantic router's ordering
+ tool_map = {self._extract_tool_info(t)[0]: t for t in matched_tools}
+ return [tool_map[name] for name in tool_names if name in tool_map]
+
+ def extract_user_query(self, messages: List[Dict[str, Any]]) -> str:
+ """
+ Extract user query from messages for /chat/completions or /responses.
+
+ Args:
+ messages: List of message dictionaries (from 'messages' or 'input' field)
+
+ Returns:
+ Extracted query string
+ """
+ for msg in reversed(messages):
+ if msg.get("role") == "user":
+ content = msg.get("content", "")
+
+ if isinstance(content, str):
+ return content
+
+ if isinstance(content, list):
+ texts = [
+ block.get("text", "") if isinstance(block, dict) else str(block)
+ for block in content
+ if isinstance(block, (dict, str))
+ ]
+ return " ".join(texts)
+
+ return ""
diff --git a/litellm/proxy/_experimental/mcp_server/server.py b/litellm/proxy/_experimental/mcp_server/server.py
index 03652ae155e..890c4ae8fb2 100644
--- a/litellm/proxy/_experimental/mcp_server/server.py
+++ b/litellm/proxy/_experimental/mcp_server/server.py
@@ -5,13 +5,24 @@ LiteLLM MCP Server Routes
import asyncio
import contextlib
-from datetime import datetime
import traceback
import uuid
-from typing import Any, AsyncIterator, Dict, List, Optional, Tuple, Union, cast
+from datetime import datetime
+from typing import (
+ Any,
+ AsyncIterator,
+ Callable,
+ Dict,
+ List,
+ Optional,
+ Tuple,
+ Union,
+ cast,
+)
from fastapi import FastAPI, HTTPException
from pydantic import AnyUrl, ConfigDict
+from starlette.requests import Request as StarletteRequest
from starlette.types import Receive, Scope, Send
from litellm._logging import verbose_logger
@@ -26,6 +37,7 @@ from litellm.proxy._experimental.mcp_server.utils import (
LITELLM_MCP_SERVER_VERSION,
)
from litellm.proxy._types import UserAPIKeyAuth
+from litellm.proxy.auth.ip_address_utils import IPAddressUtils
from litellm.types.mcp import MCPAuth
from litellm.types.mcp_server.mcp_server_manager import MCPInfo, MCPServer
from litellm.types.utils import CallTypes, StandardLoggingMCPToolCall
@@ -74,7 +86,11 @@ if MCP_AVAILABLE:
AuthContextMiddleware,
auth_context_var,
)
- from mcp.server.streamable_http_manager import StreamableHTTPSessionManager
+
+ try:
+ from mcp.server.streamable_http_manager import StreamableHTTPSessionManager
+ except ImportError:
+ StreamableHTTPSessionManager = None # type: ignore
from mcp.types import (
CallToolResult,
EmbeddedResource,
@@ -124,8 +140,8 @@ if MCP_AVAILABLE:
session_manager = StreamableHTTPSessionManager(
app=server,
event_store=None,
- json_response=True, # Use JSON responses instead of SSE by default
- stateless=True,
+ json_response=False, # enables SSE streaming
+ stateless=False, # enables session state
)
# Create SSE session manager
@@ -210,6 +226,7 @@ if MCP_AVAILABLE:
mcp_server_auth_headers,
oauth2_headers,
raw_headers,
+ _client_ip,
) = get_auth_context()
verbose_logger.debug(
f"MCP list_tools - User API Key Auth from context: {user_api_key_auth}"
@@ -273,11 +290,36 @@ if MCP_AVAILABLE:
mcp_server_auth_headers,
oauth2_headers,
raw_headers,
+ _client_ip,
) = get_auth_context()
verbose_logger.debug(
f"MCP mcp_server_tool_call - User API Key Auth from context: {user_api_key_auth}"
)
+ host_progress_callback = None
+ try:
+ host_ctx = server.request_context
+ if host_ctx and hasattr(host_ctx, 'meta') and host_ctx.meta:
+ host_token = getattr(host_ctx.meta, 'progressToken', None)
+ if host_token and hasattr(host_ctx, 'session') and host_ctx.session:
+ host_session = host_ctx.session
+
+ async def forward_progress(progress: float, total: float | None):
+ """Forward progress notifications from external MCP to Host"""
+ try:
+ await host_session.send_progress_notification(
+ progress_token=host_token,
+ progress=progress,
+ total=total
+ )
+ verbose_logger.debug(f"Forwarded progress {progress}/{total} to Host")
+ except Exception as e:
+ verbose_logger.error(f"Failed to forward progress to Host: {e}")
+
+ host_progress_callback = forward_progress
+ verbose_logger.debug(f"Host progressToken captured: {host_token[:8]}...")
+ except Exception as e:
+ verbose_logger.warning(f"Could not capture host progress context: {e}")
try:
# Create a body date for logging
body_data = {"name": name, "arguments": arguments}
@@ -307,6 +349,7 @@ if MCP_AVAILABLE:
mcp_server_auth_headers=mcp_server_auth_headers,
oauth2_headers=oauth2_headers,
raw_headers=raw_headers,
+ host_progress_callback=host_progress_callback,
**data, # for logging
)
except BlockedPiiEntityError as e:
@@ -359,6 +402,7 @@ if MCP_AVAILABLE:
mcp_server_auth_headers,
oauth2_headers,
raw_headers,
+ _client_ip,
) = get_auth_context()
verbose_logger.debug(
f"MCP list_prompts - User API Key Auth from context: {user_api_key_auth}"
@@ -412,6 +456,7 @@ if MCP_AVAILABLE:
mcp_server_auth_headers,
oauth2_headers,
raw_headers,
+ _client_ip,
) = get_auth_context()
verbose_logger.debug(
@@ -439,6 +484,7 @@ if MCP_AVAILABLE:
mcp_server_auth_headers,
oauth2_headers,
raw_headers,
+ _client_ip,
) = get_auth_context()
verbose_logger.debug(
f"MCP list_resources - User API Key Auth from context: {user_api_key_auth}"
@@ -477,6 +523,7 @@ if MCP_AVAILABLE:
mcp_server_auth_headers,
oauth2_headers,
raw_headers,
+ _client_ip,
) = get_auth_context()
verbose_logger.debug(
f"MCP list_resource_templates - User API Key Auth from context: {user_api_key_auth}"
@@ -516,6 +563,7 @@ if MCP_AVAILABLE:
mcp_server_auth_headers,
oauth2_headers,
raw_headers,
+ _client_ip,
) = get_auth_context()
read_resource_result = await mcp_read_resource(
@@ -674,13 +722,57 @@ if MCP_AVAILABLE:
return tools_to_return
+ def _get_client_ip_from_context() -> Optional[str]:
+ """
+ Extract client_ip from auth context.
+ Returns None if context not set (caller should handle this as "no IP filtering").
+ """
+ try:
+ auth_user = auth_context_var.get()
+ if auth_user and isinstance(auth_user, MCPAuthenticatedUser):
+ return auth_user.client_ip
+ except Exception:
+ pass
+ return None
+
async def _get_allowed_mcp_servers(
user_api_key_auth: Optional[UserAPIKeyAuth],
mcp_servers: Optional[List[str]],
+ client_ip: Optional[str] = None,
) -> List[MCPServer]:
- """Return allowed MCP servers for a request after applying filters."""
+ """Return allowed MCP servers for a request after applying filters.
+
+ Args:
+ user_api_key_auth: The authenticated user's API key info.
+ mcp_servers: Optional list of server names to filter to.
+ client_ip: Client IP for IP-based access control. If None, falls back to
+ auth context. Pass explicitly from request handlers for safety.
+ Note: If client_ip is None and auth context is not set, IP filtering is skipped.
+ This is intentional for internal callers but may indicate a bug if called
+ from a request handler without proper context setup.
+ """
+ # Use explicit client_ip if provided, otherwise try auth context
+ if client_ip is None:
+ client_ip = _get_client_ip_from_context()
+ if client_ip is None:
+ verbose_logger.debug(
+ "MCP _get_allowed_mcp_servers called without client_ip and no auth context. "
+ "IP filtering will be skipped. This is expected for internal calls."
+ )
+
allowed_mcp_server_ids = (
- await global_mcp_server_manager.get_allowed_mcp_servers(user_api_key_auth)
+ await global_mcp_server_manager.get_allowed_mcp_servers(
+ user_api_key_auth
+ )
+ )
+ allowed_mcp_server_ids = (
+ global_mcp_server_manager.filter_server_ids_by_ip(
+ allowed_mcp_server_ids, client_ip
+ )
+ )
+ verbose_logger.debug(
+ "MCP IP filter: client_ip=%s, allowed_server_ids=%s",
+ client_ip, allowed_mcp_server_ids,
)
allowed_mcp_servers: List[MCPServer] = []
for allowed_mcp_server_id in allowed_mcp_server_ids:
@@ -1341,6 +1433,7 @@ if MCP_AVAILABLE:
mcp_server_auth_headers: Optional[Dict[str, Dict[str, str]]] = None,
oauth2_headers: Optional[Dict[str, str]] = None,
raw_headers: Optional[Dict[str, str]] = None,
+ host_progress_callback: Optional[Callable] = None,
**kwargs: Any,
) -> CallToolResult:
"""
@@ -1438,6 +1531,7 @@ if MCP_AVAILABLE:
oauth2_headers=oauth2_headers,
raw_headers=raw_headers,
litellm_logging_obj=litellm_logging_obj,
+ host_progress_callback=host_progress_callback,
)
# Fall back to local tool registry with original name (legacy support)
@@ -1685,6 +1779,7 @@ if MCP_AVAILABLE:
oauth2_headers: Optional[Dict[str, str]] = None,
raw_headers: Optional[Dict[str, str]] = None,
litellm_logging_obj: Optional[Any] = None,
+ host_progress_callback: Optional[Callable] = None,
) -> CallToolResult:
"""Handle tool execution for managed server tools"""
# Import here to avoid circular import
@@ -1700,6 +1795,7 @@ if MCP_AVAILABLE:
oauth2_headers=oauth2_headers,
raw_headers=raw_headers,
proxy_logging_obj=proxy_logging_obj,
+ host_progress_callback=host_progress_callback,
)
verbose_logger.debug("CALL TOOL RESULT: %s", call_tool_result)
return call_tool_result
@@ -1808,6 +1904,43 @@ if MCP_AVAILABLE:
raw_headers,
)
+ def _strip_stale_mcp_session_header(
+ scope: Scope,
+ mgr: "StreamableHTTPSessionManager",
+ ) -> None:
+ """
+ Strip stale ``mcp-session-id`` headers so the session manager
+ creates a fresh session instead of returning 404 "Session not found".
+
+ When clients like VSCode reconnect after a reload they may resend a
+ session id that has already been cleaned up. Rather than letting the
+ SDK return a 404 error loop, we detect the stale id and remove the
+ header so a brand-new session is created transparently.
+
+ Fixes https://github.com/BerriAI/litellm/issues/20292
+ """
+ _mcp_session_header = b"mcp-session-id"
+ _session_id: Optional[str] = None
+ for header_name, header_value in scope.get("headers", []):
+ if header_name == _mcp_session_header:
+ _session_id = header_value.decode("utf-8", errors="replace")
+ break
+
+ if _session_id is None:
+ return
+
+ known_sessions = getattr(mgr, "_server_instances", None)
+ if known_sessions is not None and _session_id not in known_sessions:
+ verbose_logger.warning(
+ "MCP session ID '%s' not found in active sessions. "
+ "Stripping stale header to force new session creation.",
+ _session_id,
+ )
+ scope["headers"] = [
+ (k, v) for k, v in scope["headers"]
+ if k != _mcp_session_header
+ ]
+
async def handle_streamable_http_mcp(
scope: Scope, receive: Receive, send: Send
) -> None:
@@ -1822,6 +1955,10 @@ if MCP_AVAILABLE:
oauth2_headers,
raw_headers,
) = await extract_mcp_auth_context(scope, path)
+
+ # Extract client IP for MCP access control
+ _client_ip = IPAddressUtils.get_mcp_client_ip(StarletteRequest(scope))
+
verbose_logger.debug(
f"MCP request mcp_servers (header/path): {mcp_servers}"
)
@@ -1830,11 +1967,11 @@ if MCP_AVAILABLE:
)
# https://datatracker.ietf.org/doc/html/rfc9728#name-www-authenticate-response
for server_name in mcp_servers or []:
- server = global_mcp_server_manager.get_mcp_server_by_name(server_name)
+ server = global_mcp_server_manager.get_mcp_server_by_name(
+ server_name, client_ip=_client_ip
+ )
if server and server.auth_type == MCPAuth.oauth2 and not oauth2_headers:
- from starlette.requests import Request
-
- request = Request(scope)
+ request = StarletteRequest(scope)
base_url = str(request.base_url).rstrip("/")
authorization_uri = (
@@ -1856,6 +1993,7 @@ if MCP_AVAILABLE:
mcp_server_auth_headers=mcp_server_auth_headers,
oauth2_headers=oauth2_headers,
raw_headers=raw_headers,
+ client_ip=_client_ip,
)
# Ensure session managers are initialized
@@ -1864,13 +2002,16 @@ if MCP_AVAILABLE:
# Give it a moment to start up
await asyncio.sleep(0.1)
+ _strip_stale_mcp_session_header(scope, session_manager)
+
await session_manager.handle_request(scope, receive, send)
+ except HTTPException:
+ # Re-raise HTTP exceptions to preserve status codes and details
+ raise
except Exception as e:
- raise e
verbose_logger.exception(f"Error handling MCP request: {e}")
- # Instead of re-raising, try to send a graceful error response
+ # Try to send a graceful error response for non-HTTP exceptions
try:
- # Send a proper HTTP error response instead of letting the exception bubble up
from starlette.responses import JSONResponse
from starlette.status import HTTP_500_INTERNAL_SERVER_ERROR
@@ -1898,6 +2039,10 @@ if MCP_AVAILABLE:
oauth2_headers,
raw_headers,
) = await extract_mcp_auth_context(scope, path)
+
+ # Extract client IP for MCP access control
+ _sse_client_ip = IPAddressUtils.get_mcp_client_ip(StarletteRequest(scope))
+
verbose_logger.debug(
f"MCP request mcp_servers (header/path): {mcp_servers}"
)
@@ -1911,6 +2056,7 @@ if MCP_AVAILABLE:
mcp_server_auth_headers=mcp_server_auth_headers,
oauth2_headers=oauth2_headers,
raw_headers=raw_headers,
+ client_ip=_sse_client_ip,
)
if not _SESSION_MANAGERS_INITIALIZED:
@@ -1974,6 +2120,7 @@ if MCP_AVAILABLE:
mcp_server_auth_headers: Optional[Dict[str, Dict[str, str]]] = None,
oauth2_headers: Optional[Dict[str, str]] = None,
raw_headers: Optional[Dict[str, str]] = None,
+ client_ip: Optional[str] = None,
) -> None:
"""
Set the UserAPIKeyAuth in the auth context variable.
@@ -1983,6 +2130,7 @@ if MCP_AVAILABLE:
mcp_auth_header: MCP auth header to be passed to the MCP server (deprecated)
mcp_servers: Optional list of server names and access groups to filter by
mcp_server_auth_headers: Optional dict of server-specific auth headers {server_alias: auth_value}
+ client_ip: Client IP address for MCP access control
"""
auth_user = MCPAuthenticatedUser(
user_api_key_auth=user_api_key_auth,
@@ -1991,6 +2139,7 @@ if MCP_AVAILABLE:
mcp_server_auth_headers=mcp_server_auth_headers,
oauth2_headers=oauth2_headers,
raw_headers=raw_headers,
+ client_ip=client_ip,
)
auth_context_var.set(auth_user)
@@ -2002,14 +2151,15 @@ if MCP_AVAILABLE:
Optional[Dict[str, Dict[str, str]]],
Optional[Dict[str, str]],
Optional[Dict[str, str]],
+ Optional[str],
]
):
"""
Get the UserAPIKeyAuth from the auth context variable.
Returns:
- Tuple[Optional[UserAPIKeyAuth], Optional[str], Optional[List[str]], Optional[Dict[str, str]]]:
- UserAPIKeyAuth object, MCP auth header (deprecated), MCP servers (can include access groups), and server-specific auth headers
+ Tuple containing: UserAPIKeyAuth, MCP auth header (deprecated),
+ MCP servers, server-specific auth headers, OAuth2 headers, raw headers, client IP
"""
auth_user = auth_context_var.get()
if auth_user and isinstance(auth_user, MCPAuthenticatedUser):
@@ -2020,8 +2170,9 @@ if MCP_AVAILABLE:
auth_user.mcp_server_auth_headers,
auth_user.oauth2_headers,
auth_user.raw_headers,
+ auth_user.client_ip,
)
- return None, None, None, None, None, None
+ return None, None, None, None, None, None, None
########################################################
############ End of Auth Context Functions #############
diff --git a/litellm/proxy/_experimental/mcp_server/utils.py b/litellm/proxy/_experimental/mcp_server/utils.py
index d801b312aac..8189f212bcb 100644
--- a/litellm/proxy/_experimental/mcp_server/utils.py
+++ b/litellm/proxy/_experimental/mcp_server/utils.py
@@ -1,7 +1,7 @@
"""
MCP Server Utilities
"""
-from typing import Tuple, Any
+from typing import Any, Dict, Mapping, Optional, Tuple
import os
import importlib
@@ -137,3 +137,31 @@ def validate_mcp_server_name(
)
else:
raise Exception(error_message)
+
+
+def merge_mcp_headers(
+ *,
+ extra_headers: Optional[Mapping[str, str]] = None,
+ static_headers: Optional[Mapping[str, str]] = None,
+) -> Optional[Dict[str, str]]:
+ """Merge outbound HTTP headers for MCP calls.
+
+ This is used when calling out to external MCP servers (or OpenAPI-based MCP tools).
+
+ Merge rules:
+ - Start with `extra_headers` (typically OAuth2-derived headers)
+ - Overlay `static_headers` (user-configured per MCP server)
+
+ If both contain the same key, `static_headers` wins. This matches the existing
+ behavior in `MCPServerManager` where `server.static_headers` is applied after
+ any caller-provided headers.
+ """
+ merged: Dict[str, str] = {}
+
+ if extra_headers:
+ merged.update({str(k): str(v) for k, v in extra_headers.items()})
+
+ if static_headers:
+ merged.update({str(k): str(v) for k, v in static_headers.items()})
+
+ return merged or None
diff --git a/litellm/proxy/_experimental/out/404.html b/litellm/proxy/_experimental/out/404.html
new file mode 100644
index 00000000000..63f46b9c025
--- /dev/null
+++ b/litellm/proxy/_experimental/out/404.html
@@ -0,0 +1 @@
+404: This page could not be found.LiteLLM Dashboard