mirror of
https://github.com/BerriAI/litellm.git
synced 2026-10-11 03:38:38 +00:00
Merge branch 'main' into litellm_oss_staging_01_28_2026
This commit is contained in:
 Sameer Kankute
GitHub
commit
df072979e5
366 changed files with 8231 additions and 1439 deletions
|
|
@ -715,8 +715,8 @@ jobs:
|
|||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml litellm_router_coverage.xml
|
||||
mv .coverage litellm_router_coverage
|
||||
mv coverage.xml litellm_router_unit_coverage.xml
|
||||
mv .coverage litellm_router_unit_coverage
|
||||
# Store test results
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
|
|
@ -724,8 +724,8 @@ jobs:
|
|||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm_router_coverage.xml
|
||||
- litellm_router_coverage
|
||||
- litellm_router_unit_coverage.xml
|
||||
- litellm_router_unit_coverage
|
||||
litellm_security_tests:
|
||||
machine:
|
||||
image: ubuntu-2204:2023.10.1
|
||||
|
|
@ -3428,7 +3428,7 @@ jobs:
|
|||
python -m venv venv
|
||||
. venv/bin/activate
|
||||
pip install coverage
|
||||
coverage combine llm_translation_coverage llm_responses_api_coverage ocr_coverage search_coverage mcp_coverage logging_coverage audio_coverage litellm_router_coverage local_testing_part1_coverage local_testing_part2_coverage litellm_assistants_api_coverage auth_ui_unit_tests_coverage langfuse_coverage caching_coverage litellm_proxy_unit_tests_part1_coverage litellm_proxy_unit_tests_part2_coverage image_gen_coverage pass_through_unit_tests_coverage batches_coverage litellm_security_tests_coverage guardrails_coverage litellm_mapped_tests_coverage
|
||||
coverage combine llm_translation_coverage llm_responses_api_coverage ocr_coverage search_coverage mcp_coverage logging_coverage audio_coverage litellm_router_coverage litellm_router_unit_coverage local_testing_part1_coverage local_testing_part2_coverage litellm_assistants_api_coverage auth_ui_unit_tests_coverage langfuse_coverage caching_coverage litellm_proxy_unit_tests_part1_coverage litellm_proxy_unit_tests_part2_coverage image_gen_coverage pass_through_unit_tests_coverage batches_coverage litellm_security_tests_coverage guardrails_coverage litellm_mapped_tests_coverage
|
||||
coverage xml
|
||||
- codecov/upload:
|
||||
file: ./coverage.xml
|
||||
|
|
@ -3478,8 +3478,22 @@ jobs:
|
|||
ls dist/
|
||||
twine upload --verbose dist/*
|
||||
else
|
||||
echo "Version ${VERSION} of package is already published on PyPI. Skipping PyPI publish."
|
||||
circleci step halt
|
||||
echo "Version ${VERSION} of package is already published on PyPI."
|
||||
|
||||
# Check if corresponding Docker nightly image exists
|
||||
NIGHTLY_TAG="v${VERSION}-nightly"
|
||||
echo "Checking for Docker nightly image: litellm/litellm:${NIGHTLY_TAG}"
|
||||
|
||||
# Check Docker Hub for the nightly image
|
||||
if curl -s "https://hub.docker.com/v2/repositories/litellm/litellm/tags/${NIGHTLY_TAG}" | grep -q "name"; then
|
||||
echo "Docker nightly image ${NIGHTLY_TAG} exists. This release was already completed successfully."
|
||||
echo "Skipping PyPI publish and continuing to ensure Docker images are up to date."
|
||||
circleci step halt
|
||||
else
|
||||
echo "ERROR: PyPI package ${VERSION} exists but Docker nightly image ${NIGHTLY_TAG} does not exist!"
|
||||
echo "This indicates an incomplete release. Please investigate."
|
||||
exit 1
|
||||
fi
|
||||
fi
|
||||
- run:
|
||||
name: Trigger Github Action for new Docker Container + Trigger Load Testing
|
||||
|
|
@ -3488,11 +3502,21 @@ jobs:
|
|||
python3 -m pip install toml
|
||||
VERSION=$(python3 -c "import toml; print(toml.load('pyproject.toml')['tool']['poetry']['version'])")
|
||||
echo "LiteLLM Version ${VERSION}"
|
||||
|
||||
# Determine which branch to use for Docker build
|
||||
if [[ "$CIRCLE_BRANCH" =~ ^litellm_release_day_.* ]]; then
|
||||
BUILD_BRANCH="$CIRCLE_BRANCH"
|
||||
echo "Using release branch: $BUILD_BRANCH"
|
||||
else
|
||||
BUILD_BRANCH="main"
|
||||
echo "Using default branch: $BUILD_BRANCH"
|
||||
fi
|
||||
|
||||
curl -X POST \
|
||||
-H "Accept: application/vnd.github.v3+json" \
|
||||
-H "Authorization: Bearer $GITHUB_TOKEN" \
|
||||
"https://api.github.com/repos/BerriAI/litellm/actions/workflows/ghcr_deploy.yml/dispatches" \
|
||||
-d "{\"ref\":\"main\", \"inputs\":{\"tag\":\"v${VERSION}-nightly\", \"commit_hash\":\"$CIRCLE_SHA1\"}}"
|
||||
-d "{\"ref\":\"${BUILD_BRANCH}\", \"inputs\":{\"tag\":\"v${VERSION}-nightly\", \"commit_hash\":\"$CIRCLE_SHA1\"}}"
|
||||
echo "triggering load testing server for version ${VERSION} and commit ${CIRCLE_SHA1}"
|
||||
curl -X POST "https://proxyloadtester-production.up.railway.app/start/load/test?version=${VERSION}&commit_hash=${CIRCLE_SHA1}&release_type=nightly"
|
||||
|
||||
|
|
@ -4235,6 +4259,7 @@ workflows:
|
|||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_release_day_.*/
|
||||
- publish_to_pypi:
|
||||
requires:
|
||||
- mypy_linting
|
||||
|
|
|
|||
2
.github/workflows/test-linting.yml
vendored
2
.github/workflows/test-linting.yml
vendored
|
|
@ -73,4 +73,4 @@ jobs:
|
|||
|
||||
- name: Check import safety
|
||||
run: |
|
||||
poetry run python -c "from litellm import *" || (echo '🚨 import failed, this means you introduced unprotected imports! 🚨'; exit 1)
|
||||
poetry run python -c "from litellm import *" || (echo '🚨 import failed, this means you introduced unprotected imports! 🚨'; exit 1)
|
||||
|
|
|
|||
2
.github/workflows/test-litellm.yml
vendored
2
.github/workflows/test-litellm.yml
vendored
|
|
@ -34,7 +34,7 @@ jobs:
|
|||
poetry run pip install "google-genai==1.22.0"
|
||||
poetry run pip install "google-cloud-aiplatform>=1.38"
|
||||
poetry run pip install "fastapi-offline==1.7.3"
|
||||
poetry run pip install "python-multipart==0.0.18"
|
||||
poetry run pip install "python-multipart==0.0.22"
|
||||
poetry run pip install "openapi-core"
|
||||
- name: Setup litellm-enterprise as local package
|
||||
run: |
|
||||
|
|
|
|||
15
.github/workflows/test-model-map.yaml
vendored
Normal file
15
.github/workflows/test-model-map.yaml
vendored
Normal file
|
|
@ -0,0 +1,15 @@
|
|||
name: Validate model_prices_and_context_window.json
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [ main ]
|
||||
|
||||
jobs:
|
||||
validate-model-prices-json:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v4
|
||||
|
||||
- name: Validate model_prices_and_context_window.json
|
||||
run: |
|
||||
jq empty model_prices_and_context_window.json
|
||||
8
.gitignore
vendored
8
.gitignore
vendored
|
|
@ -60,10 +60,6 @@ litellm/proxy/_super_secret_config.yaml
|
|||
litellm/proxy/myenv/bin/activate
|
||||
litellm/proxy/myenv/bin/Activate.ps1
|
||||
myenv/*
|
||||
litellm/proxy/_experimental/out/_next/
|
||||
litellm/proxy/_experimental/out/404/index.html
|
||||
litellm/proxy/_experimental/out/model_hub/index.html
|
||||
litellm/proxy/_experimental/out/onboarding/index.html
|
||||
litellm/tests/log.txt
|
||||
litellm/tests/langfuse.log
|
||||
litellm/tests/langfuse.log
|
||||
|
|
@ -76,9 +72,6 @@ tests/local_testing/log.txt
|
|||
litellm/proxy/_new_new_secret_config.yaml
|
||||
litellm/proxy/custom_guardrail.py
|
||||
.mypy_cache/*
|
||||
litellm/proxy/_experimental/out/404.html
|
||||
litellm/proxy/_experimental/out/404.html
|
||||
litellm/proxy/_experimental/out/model_hub.html
|
||||
.mypy_cache/*
|
||||
litellm/proxy/application.log
|
||||
tests/llm_translation/vertex_test_account.json
|
||||
|
|
@ -100,7 +93,6 @@ litellm_config.yaml
|
|||
litellm/proxy/to_delete_loadtest_work/*
|
||||
update_model_cost_map.py
|
||||
tests/test_litellm/proxy/_experimental/mcp_server/test_mcp_server_manager.py
|
||||
litellm/proxy/_experimental/out/guardrails/index.html
|
||||
scripts/test_vertex_ai_search.py
|
||||
LAZY_LOADING_IMPROVEMENTS.md
|
||||
**/test-results
|
||||
|
|
|
|||
|
|
@ -38,6 +38,10 @@ spec:
|
|||
serviceAccountName: {{ include "litellm.serviceAccountName" . }}
|
||||
securityContext:
|
||||
{{- toYaml .Values.podSecurityContext | nindent 8 }}
|
||||
{{- with .Values.extraInitContainers }}
|
||||
initContainers:
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- end }}
|
||||
containers:
|
||||
- name: {{ include "litellm.name" . }}
|
||||
securityContext:
|
||||
|
|
|
|||
|
|
@ -35,6 +35,10 @@ spec:
|
|||
{{- toYaml . | nindent 8 }}
|
||||
{{- end }}
|
||||
serviceAccountName: {{ include "litellm.serviceAccountName" . }}
|
||||
{{- with .Values.migrationJob.extraInitContainers }}
|
||||
initContainers:
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- end }}
|
||||
containers:
|
||||
- name: prisma-migrations
|
||||
image: "{{ .Values.image.repository }}:{{ .Values.image.tag | default (printf "main-%s" .Chart.AppVersion) }}"
|
||||
|
|
|
|||
|
|
@ -281,6 +281,7 @@ migrationJob:
|
|||
# cpu: 100m
|
||||
# memory: 100Mi
|
||||
extraContainers: []
|
||||
extraInitContainers: []
|
||||
|
||||
# Hook configuration
|
||||
hooks:
|
||||
|
|
|
|||
|
|
@ -462,6 +462,7 @@ router_settings:
|
|||
| CHATGPT_USER_AGENT_SUFFIX | Suffix to append to the ChatGPT user agent string
|
||||
| CIRCLE_OIDC_TOKEN | OpenID Connect token for CircleCI
|
||||
| CIRCLE_OIDC_TOKEN_V2 | Version 2 of the OpenID Connect token for CircleCI
|
||||
| CLI_JWT_EXPIRATION_HOURS | Expiration time in hours for CLI-generated JWT tokens. Default is 24 hours. Can also be set via LITELLM_CLI_JWT_EXPIRATION_HOURS
|
||||
| CLOUDZERO_API_KEY | CloudZero API key for authentication
|
||||
| CLOUDZERO_CONNECTION_ID | CloudZero connection ID for data submission
|
||||
| CLOUDZERO_EXPORT_INTERVAL_MINUTES | Interval in minutes for CloudZero data export operations
|
||||
|
|
@ -723,6 +724,7 @@ router_settings:
|
|||
| LITERAL_API_URL | API URL for Literal service
|
||||
| LITERAL_BATCH_SIZE | Batch size for Literal operations
|
||||
| LITELLM_ANTHROPIC_DISABLE_URL_SUFFIX | Disable automatic URL suffix appending for Anthropic API base URLs. When set to `true`, prevents LiteLLM from automatically adding `/v1/messages` or `/v1/complete` to custom Anthropic API endpoints
|
||||
| LITELLM_CLI_JWT_EXPIRATION_HOURS | Expiration time in hours for CLI-generated JWT tokens. Default is 24 hours
|
||||
| LITELLM_DD_AGENT_HOST | Hostname or IP of DataDog agent for LiteLLM-specific logging. When set, logs are sent to agent instead of direct API
|
||||
| LITELLM_DD_AGENT_PORT | Port of DataDog agent for LiteLLM-specific log intake. Default is 10518
|
||||
| LITELLM_DONT_SHOW_FEEDBACK_BOX | Flag to hide feedback box in LiteLLM UI
|
||||
|
|
|
|||
|
|
@ -405,14 +405,10 @@ curl --location 'http://0.0.0.0:4000/chat/completions' \
|
|||
|
||||
## **Proxy Admin Controls**
|
||||
|
||||
### ✨ Monitoring Guardrails
|
||||
### Monitoring Guardrails
|
||||
|
||||
Monitor which guardrails were executed and whether they passed or failed. e.g. guardrail going rogue and failing requests we don't intend to fail
|
||||
|
||||
:::info
|
||||
|
||||
✨ This is an Enterprise only feature [Get a free trial](https://www.litellm.ai/enterprise#trial)
|
||||
|
||||
:::
|
||||
|
||||
#### Setup
|
||||
|
|
|
|||
|
|
@ -121,8 +121,8 @@ Use this to track overall LiteLLM Proxy usage.
|
|||
|
||||
| Metric Name | Description |
|
||||
|----------------------|--------------------------------------|
|
||||
| `litellm_proxy_failed_requests_metric` | Total number of failed responses from proxy - the client did not get a success response from litellm proxy. Labels: `"end_user", "hashed_api_key", "api_key_alias", "requested_model", "team", "team_alias", "user", "exception_status", "exception_class", "route"` |
|
||||
| `litellm_proxy_total_requests_metric` | Total number of requests made to the proxy server - track number of client side requests. Labels: `"end_user", "hashed_api_key", "api_key_alias", "requested_model", "team", "team_alias", "user", "status_code", "user_email", "route"` |
|
||||
| `litellm_proxy_failed_requests_metric` | Total number of failed responses from proxy - the client did not get a success response from litellm proxy. Labels: `"end_user", "hashed_api_key", "api_key_alias", "requested_model", "team", "team_alias", "user", "user_email", "exception_status", "exception_class", "route", "model_id"` |
|
||||
| `litellm_proxy_total_requests_metric` | Total number of requests made to the proxy server - track number of client side requests. Labels: `"end_user", "hashed_api_key", "api_key_alias", "requested_model", "team", "team_alias", "user", "status_code", "user_email", "route", "model_id"` |
|
||||
|
||||
### Callback Logging Metrics
|
||||
|
||||
|
|
@ -130,7 +130,12 @@ Monitor failures while shipping logs to downstream callbacks like `s3_v3` cold s
|
|||
|
||||
| Metric Name | Description |
|
||||
|----------------------|--------------------------------------|
|
||||
| `litellm_callback_logging_failures_metric` | Total number of failed attempts to emit logs to a configured callback. Labels: `"callback_name"`. Use this to alert on callback delivery issues such as repeated failures when writing to `s3_v3`. |
|
||||
| `litellm_callback_logging_failures_metric` | Total number of failed attempts to emit logs to a configured callback. Labels: `"callback_name"`. Use this to alert on callback delivery issues such as repeated failures when writing to `s3_v3`, `langfuse`, or `langfuse_otel` and other otel providers |
|
||||
|
||||
**Supported Callbacks:**
|
||||
- `S3Logger` - S3 v2 cold storage failures
|
||||
- `langfuse` - Langfuse logging failures
|
||||
- `otel` - OpenTelemetry logging failures
|
||||
|
||||
## LLM Provider Metrics
|
||||
|
||||
|
|
@ -191,10 +196,10 @@ Use this for LLM API Error monitoring and tracking remaining rate limits and tok
|
|||
|
||||
| Metric Name | Description |
|
||||
|----------------------|--------------------------------------|
|
||||
| `litellm_request_total_latency_metric` | Total latency (seconds) for a request to LiteLLM Proxy Server - tracked for labels "end_user", "hashed_api_key", "api_key_alias", "requested_model", "team", "team_alias", "user", "model" |
|
||||
| `litellm_request_total_latency_metric` | Total latency (seconds) for a request to LiteLLM Proxy Server - tracked for labels "end_user", "hashed_api_key", "api_key_alias", "requested_model", "team", "team_alias", "user", "model", "model_id" |
|
||||
| `litellm_overhead_latency_metric` | Latency overhead (seconds) added by LiteLLM processing - tracked for labels "model_group", "api_provider", "api_base", "litellm_model_name", "hashed_api_key", "api_key_alias" |
|
||||
| `litellm_llm_api_latency_metric` | Latency (seconds) for just the LLM API call - tracked for labels "model", "hashed_api_key", "api_key_alias", "team", "team_alias", "requested_model", "end_user", "user" |
|
||||
| `litellm_llm_api_time_to_first_token_metric` | Time to first token for LLM API call - tracked for labels `model`, `hashed_api_key`, `api_key_alias`, `team`, `team_alias` [Note: only emitted for streaming requests] |
|
||||
| `litellm_llm_api_time_to_first_token_metric` | Time to first token for LLM API call - tracked for labels `model`, `hashed_api_key`, `api_key_alias`, `team`, `team_alias`, `requested_model`, `end_user`, `user`, `model_id` [Note: only emitted for streaming requests] |
|
||||
|
||||
## Tracking `end_user` on Prometheus
|
||||
|
||||
|
|
|
|||
121
docs/my-website/docs/proxy/ui/page_visibility.md
Normal file
121
docs/my-website/docs/proxy/ui/page_visibility.md
Normal file
|
|
@ -0,0 +1,121 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Control Page Visibility for Internal Users
|
||||
|
||||
Configure which navigation tabs and pages are visible to internal users (non-admin developers) in the LiteLLM UI.
|
||||
|
||||
Use this feature to simplify the UI and control which pages your internal users/developers can see when signing in.
|
||||
|
||||
## Overview
|
||||
|
||||
By default, all pages accessible to internal users are visible in the navigation sidebar. The page visibility control allows admins to restrict which pages internal users can see, creating a more focused and streamlined experience.
|
||||
|
||||
|
||||
## Configure Page Visibility
|
||||
|
||||
### 1. Navigate to Settings
|
||||
|
||||
Click the **Settings** icon in the sidebar.
|
||||
|
||||
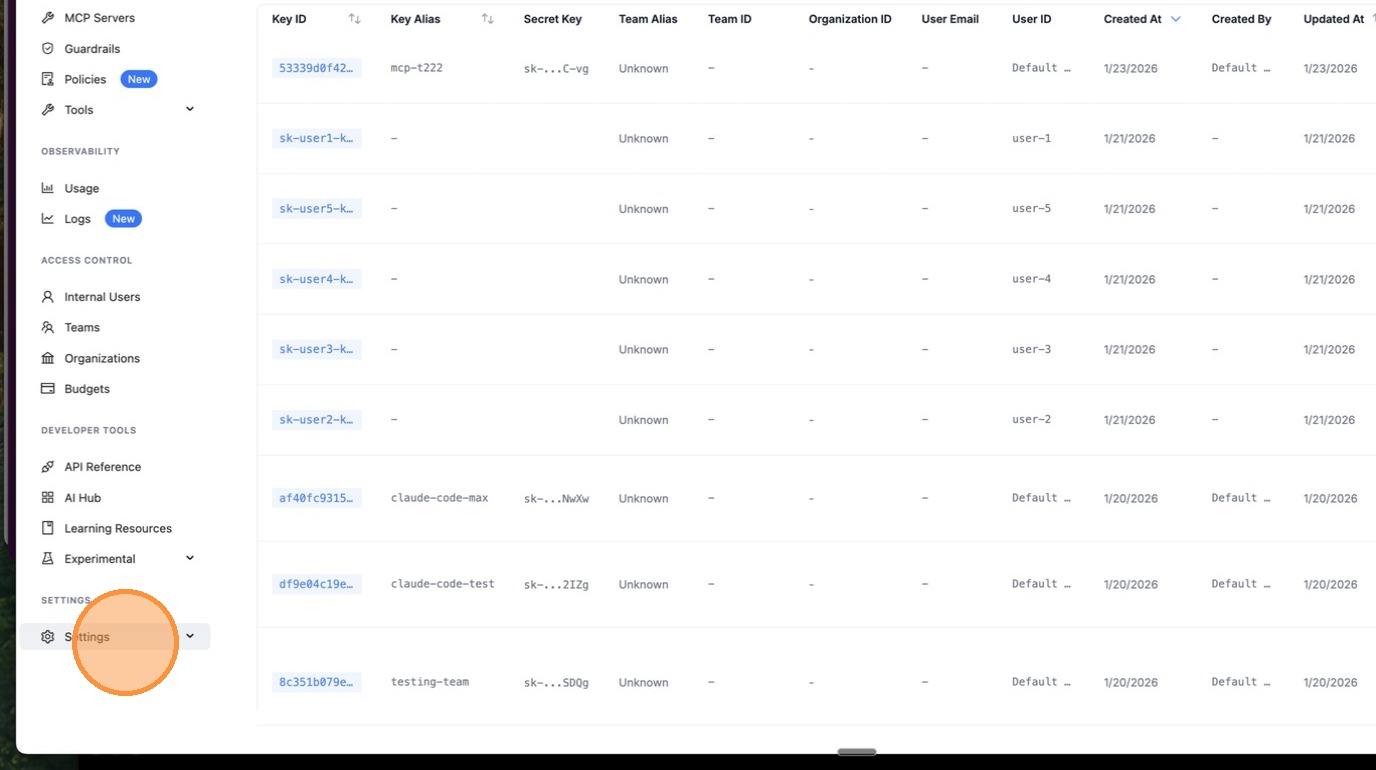
|
||||
|
||||
### 2. Go to Admin Settings
|
||||
|
||||
Click **Admin Settings** from the settings menu.
|
||||
|
||||
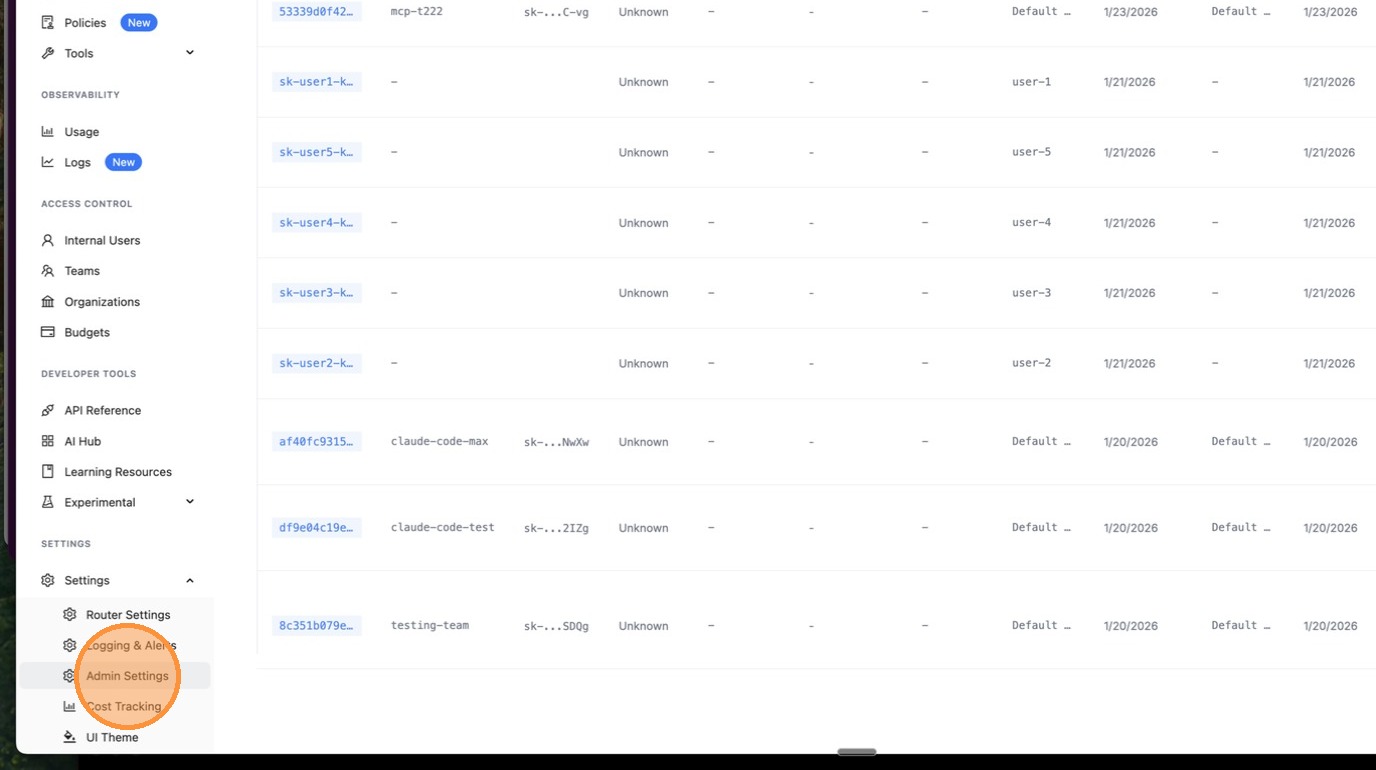
|
||||
|
||||
### 3. Select UI Settings
|
||||
|
||||
Click **UI Settings** to access the page visibility controls.
|
||||
|
||||
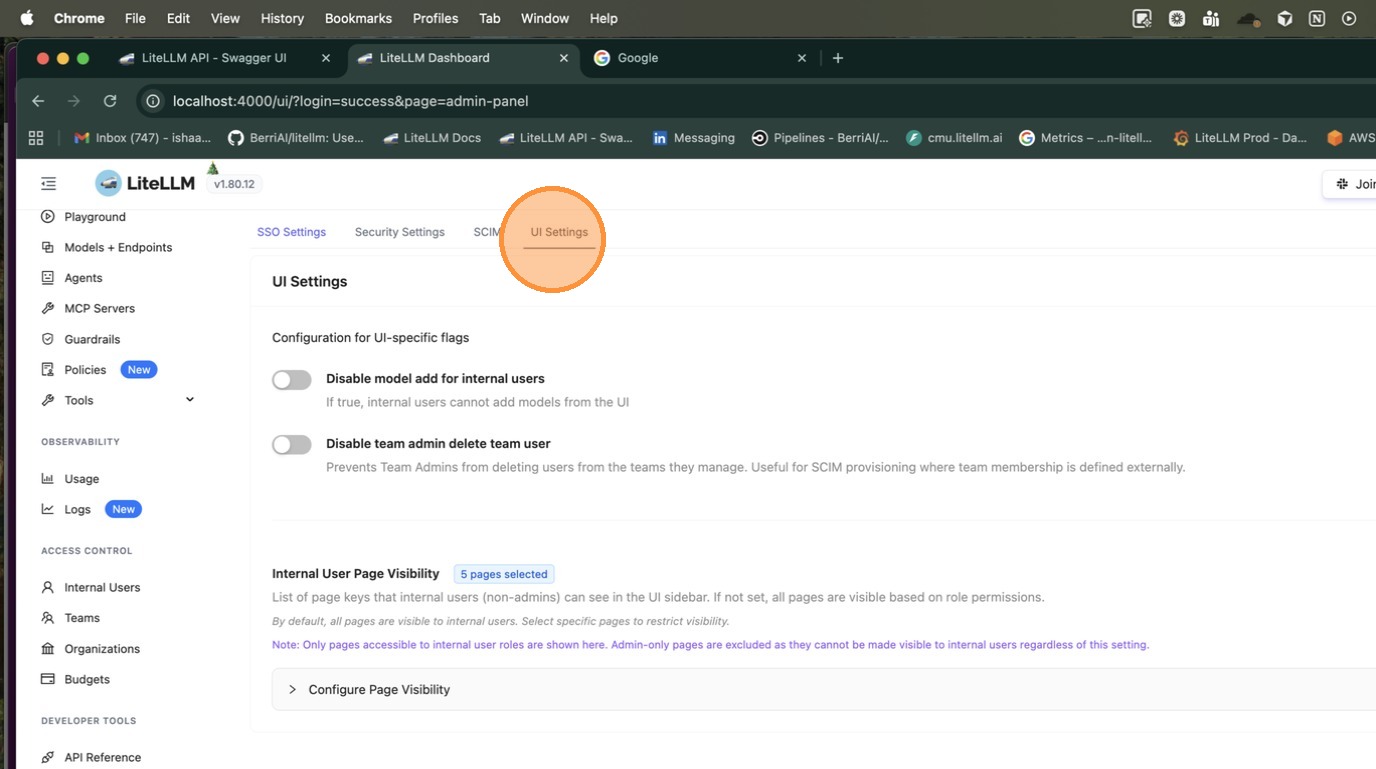
|
||||
|
||||
### 4. Open Page Visibility Configuration
|
||||
|
||||
Click **Configure Page Visibility** to expand the configuration panel.
|
||||
|
||||
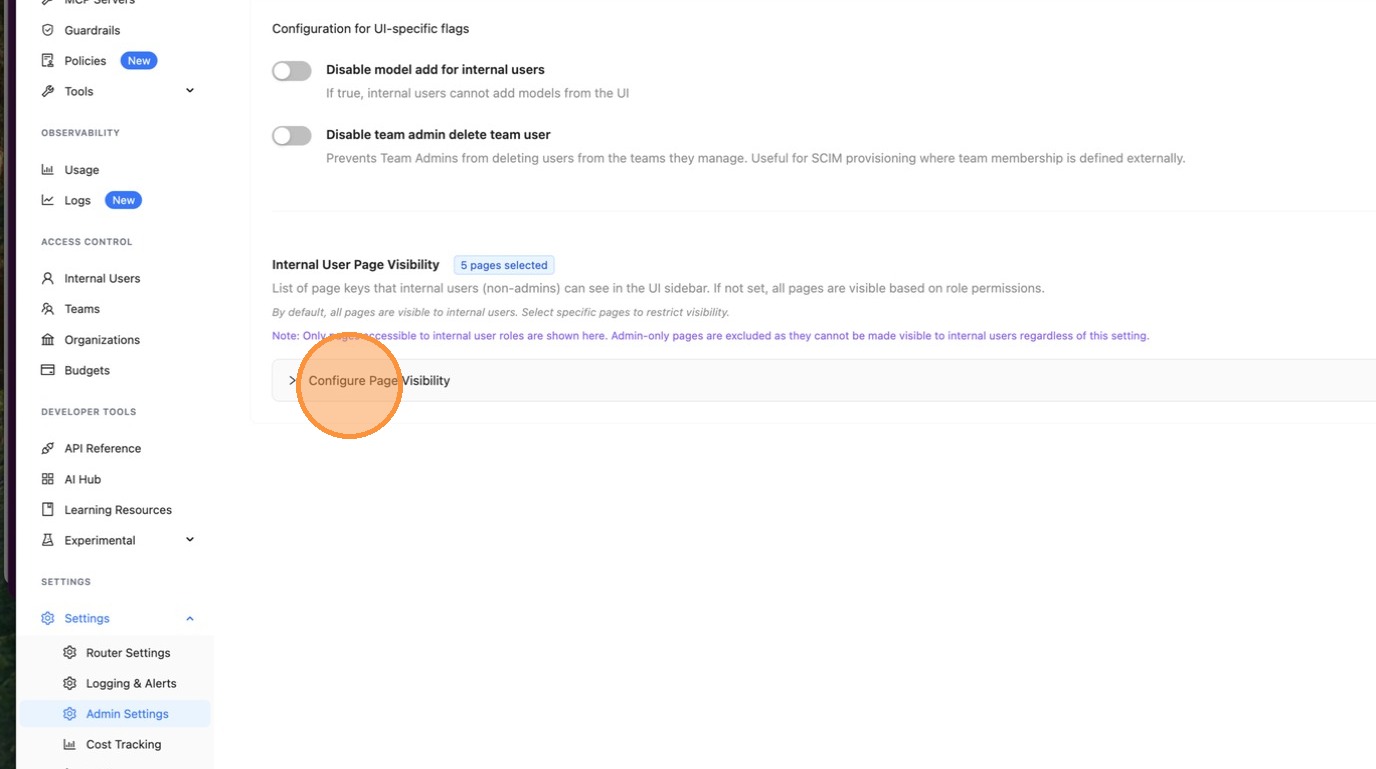
|
||||
|
||||
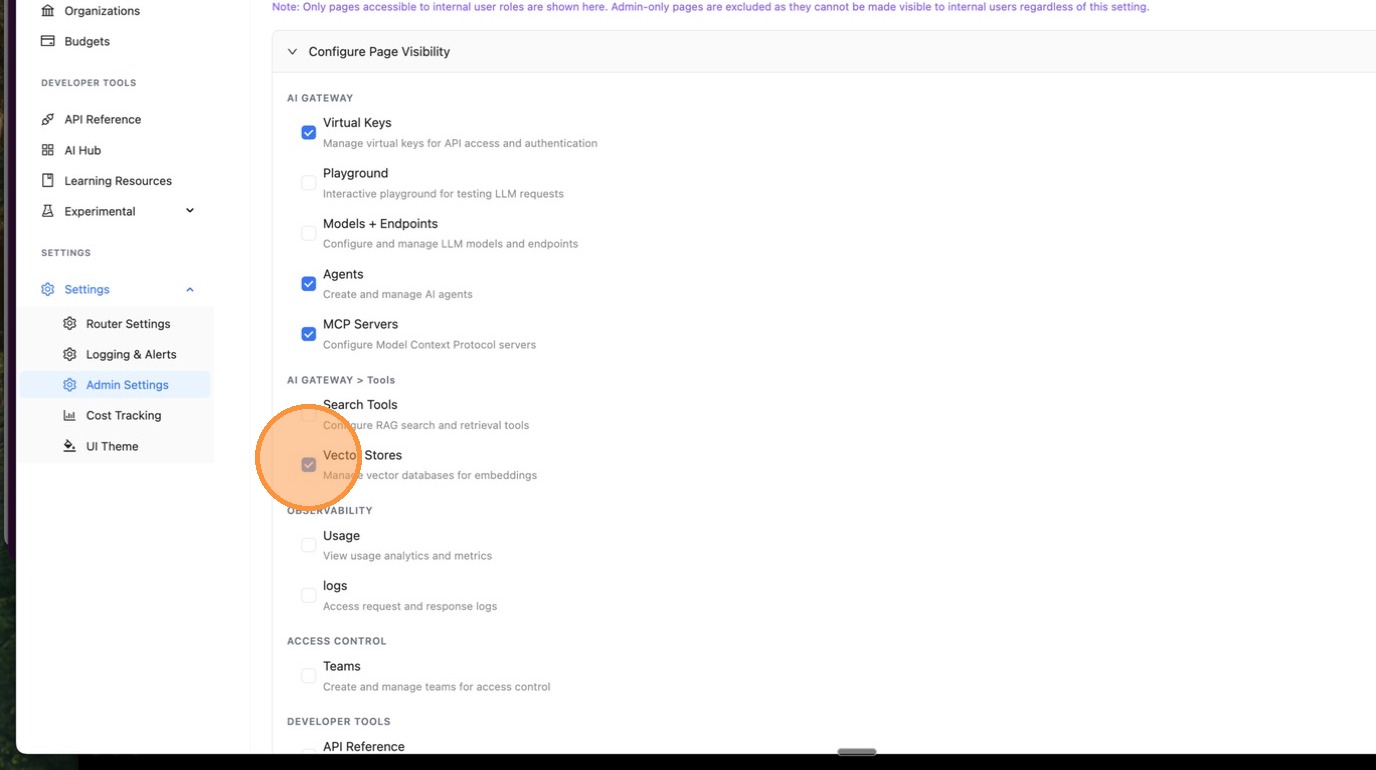
### 5. Select Pages to Make Visible
|
||||
|
||||
Check the boxes for the pages you want internal users to see. Pages are organized by category for easy navigation.
|
||||
|
||||
|
||||
|
||||
**Available pages include:**
|
||||
- Virtual Keys
|
||||
- Playground
|
||||
- Models + Endpoints
|
||||
- Agents
|
||||
- MCP Servers
|
||||
- Search Tools
|
||||
- Vector Stores
|
||||
- Logs
|
||||
- Teams
|
||||
- Organizations
|
||||
- Usage
|
||||
- Budgets
|
||||
- And more...
|
||||
|
||||
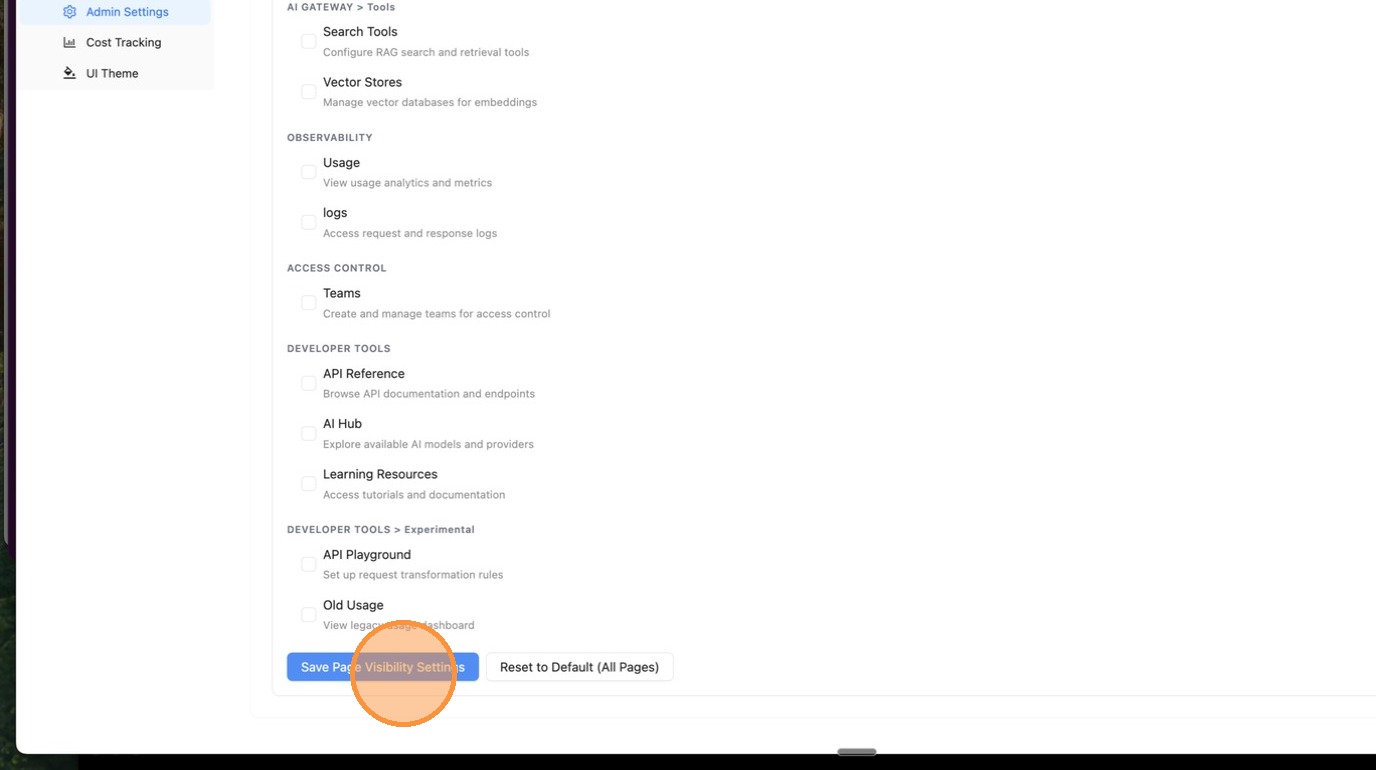
### 6. Save Your Configuration
|
||||
|
||||
Click **Save Page Visibility Settings** to apply the changes.
|
||||
|
||||
|
||||
|
||||
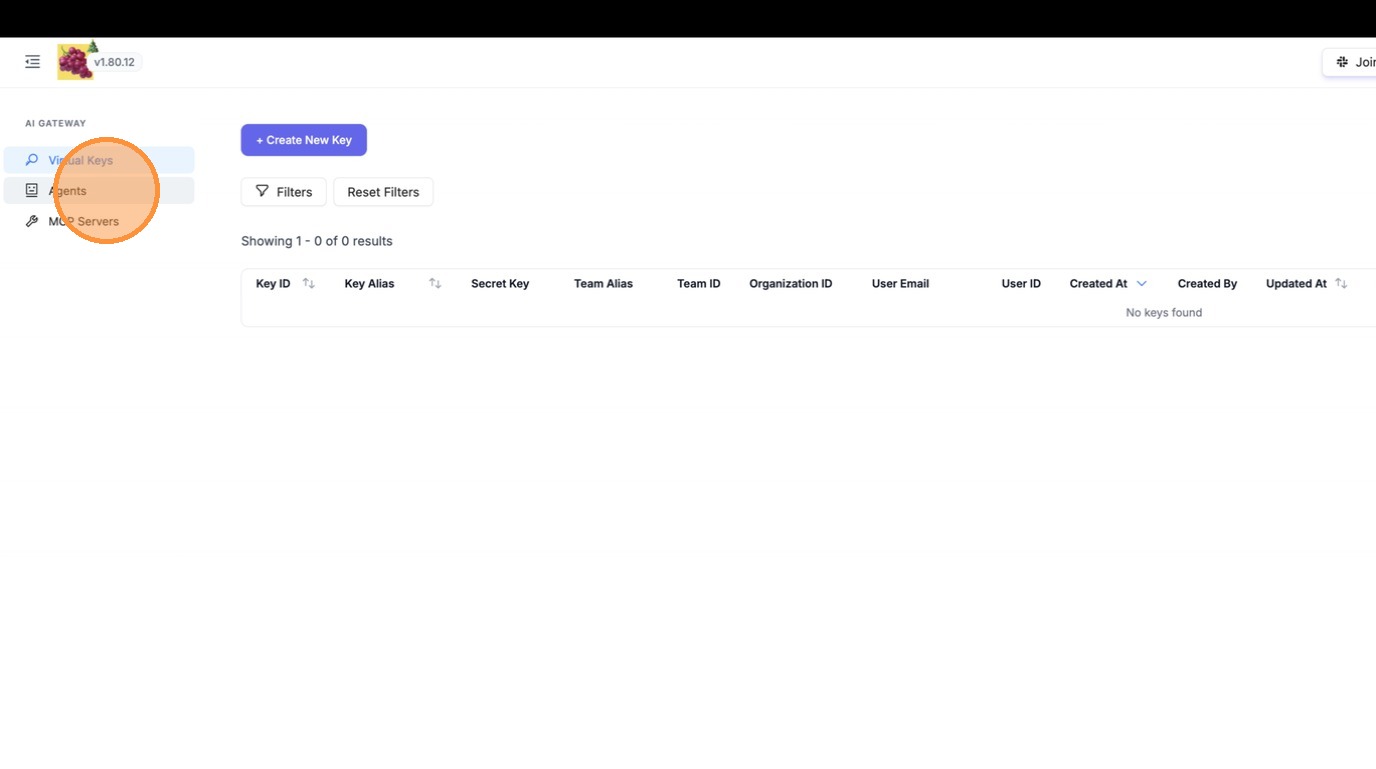
### 7. Verify Changes
|
||||
|
||||
Internal users will now only see the selected pages in their navigation sidebar.
|
||||
|
||||
|
||||
|
||||
## Reset to Default
|
||||
|
||||
To restore all pages to internal users:
|
||||
|
||||
1. Open the Page Visibility configuration
|
||||
2. Click **Reset to Default (All Pages)**
|
||||
3. Click **Save Page Visibility Settings**
|
||||
|
||||
This will clear the restriction and show all accessible pages to internal users.
|
||||
|
||||
## API Configuration
|
||||
|
||||
You can also configure page visibility programmatically using the API:
|
||||
|
||||
### Get Current Settings
|
||||
|
||||
```bash
|
||||
curl -X GET 'http://localhost:4000/ui_settings/get' \
|
||||
-H 'Authorization: Bearer <your-admin-key>'
|
||||
```
|
||||
|
||||
### Update Page Visibility
|
||||
|
||||
```bash
|
||||
curl -X PATCH 'http://localhost:4000/ui_settings/update' \
|
||||
-H 'Authorization: Bearer <your-admin-key>' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-d '{
|
||||
"enabled_ui_pages_internal_users": [
|
||||
"api-keys",
|
||||
"agents",
|
||||
"mcp-servers",
|
||||
"logs",
|
||||
"teams"
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
### Clear Page Visibility Restrictions
|
||||
|
||||
```bash
|
||||
curl -X PATCH 'http://localhost:4000/ui_settings/update' \
|
||||
-H 'Authorization: Bearer <your-admin-key>' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-d '{
|
||||
"enabled_ui_pages_internal_users": null
|
||||
}'
|
||||
```
|
||||
|
||||
|
|
@ -828,6 +828,7 @@ asyncio.run(router_acompletion())
|
|||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Traffic Mirroring / Silent Experiments
|
||||
|
||||
|
|
|
|||
|
|
@ -274,11 +274,19 @@ const sidebars = {
|
|||
"proxy/custom_sso",
|
||||
"proxy/ai_hub",
|
||||
"proxy/model_compare_ui",
|
||||
"proxy/public_teams",
|
||||
"proxy/self_serve",
|
||||
"proxy/ui/bulk_edit_users",
|
||||
"proxy/ui_credentials",
|
||||
"tutorials/scim_litellm",
|
||||
{
|
||||
type: "category",
|
||||
label: "UI User/Team Management",
|
||||
items: [
|
||||
"proxy/access_control",
|
||||
"proxy/public_teams",
|
||||
"proxy/self_serve",
|
||||
"proxy/ui/bulk_edit_users",
|
||||
"proxy/ui/page_visibility",
|
||||
]
|
||||
},
|
||||
{
|
||||
type: "category",
|
||||
label: "UI Usage Tracking",
|
||||
|
|
|
|||
|
|
@ -244,6 +244,78 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
return managed_object.created_by == user_id
|
||||
return True # don't raise error if managed object is not found
|
||||
|
||||
async def list_user_batches(
|
||||
self,
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
limit: Optional[int] = None,
|
||||
after: Optional[str] = None,
|
||||
provider: Optional[str] = None,
|
||||
target_model_names: Optional[str] = None,
|
||||
llm_router: Optional[Router] = None,
|
||||
) -> Dict[str, Any]:
|
||||
# Provider filtering is not supported for managed batches
|
||||
# This is because the encoded object ids stored in the managed objects table do not contain the provider information
|
||||
# To support provider filtering, we would need to store the provider information in the encoded object ids
|
||||
if provider:
|
||||
raise Exception(
|
||||
"Filtering by 'provider' is not supported when using managed batches."
|
||||
)
|
||||
|
||||
# Model name filtering is not supported for managed batches
|
||||
# This is because the encoded object ids stored in the managed objects table do not contain the model name
|
||||
# A hash of the model name + litellm_params for the model name is encoded as the model id. This is not sufficient to reliably map the target model names to the model ids.
|
||||
if target_model_names:
|
||||
raise Exception(
|
||||
"Filtering by 'target_model_names' is not supported when using managed batches."
|
||||
)
|
||||
|
||||
where_clause: Dict[str, Any] = {"file_purpose": "batch"}
|
||||
|
||||
# Filter by user who created the batch
|
||||
if user_api_key_dict.user_id:
|
||||
where_clause["created_by"] = user_api_key_dict.user_id
|
||||
|
||||
if after:
|
||||
where_clause["id"] = {"gt": after}
|
||||
|
||||
# Fetch more than needed to allow for post-fetch filtering
|
||||
fetch_limit = limit or 20
|
||||
if target_model_names:
|
||||
# Fetch extra to account for filtering
|
||||
fetch_limit = max(fetch_limit * 3, 100)
|
||||
|
||||
batches = await self.prisma_client.db.litellm_managedobjecttable.find_many(
|
||||
where=where_clause,
|
||||
take=fetch_limit,
|
||||
order={"created_at": "desc"},
|
||||
)
|
||||
|
||||
batch_objects: List[LiteLLMBatch] = []
|
||||
for batch in batches:
|
||||
try:
|
||||
# Stop once we have enough after filtering
|
||||
if len(batch_objects) >= (limit or 20):
|
||||
break
|
||||
|
||||
batch_data = json.loads(batch.file_object) if isinstance(batch.file_object, str) else batch.file_object
|
||||
batch_obj = LiteLLMBatch(**batch_data)
|
||||
batch_obj.id = batch.unified_object_id
|
||||
batch_objects.append(batch_obj)
|
||||
|
||||
except Exception as e:
|
||||
verbose_logger.warning(
|
||||
f"Failed to parse batch object {batch.unified_object_id}: {e}"
|
||||
)
|
||||
continue
|
||||
|
||||
return {
|
||||
"object": "list",
|
||||
"data": batch_objects,
|
||||
"first_id": batch_objects[0].id if batch_objects else None,
|
||||
"last_id": batch_objects[-1].id if batch_objects else None,
|
||||
"has_more": len(batch_objects) == (limit or 20),
|
||||
}
|
||||
|
||||
async def get_user_created_file_ids(
|
||||
self, user_api_key_dict: UserAPIKeyAuth, model_object_ids: List[str]
|
||||
) -> List[OpenAIFileObject]:
|
||||
|
|
@ -673,6 +745,7 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
bytes=file_objects[0].bytes,
|
||||
filename=file_objects[0].filename,
|
||||
status="uploaded",
|
||||
expires_at=file_objects[0].expires_at,
|
||||
)
|
||||
|
||||
return response
|
||||
|
|
|
|||
|
|
@ -760,6 +760,11 @@ model LiteLLM_ManagedVectorStoresTable {
|
|||
updated_at DateTime @updatedAt
|
||||
litellm_credential_name String?
|
||||
litellm_params Json?
|
||||
team_id String?
|
||||
user_id String?
|
||||
|
||||
@@index([team_id])
|
||||
@@index([user_id])
|
||||
}
|
||||
|
||||
// Guardrails table for storing guardrail configurations
|
||||
|
|
|
|||
|
|
@ -18,14 +18,15 @@ def str_to_bool(value: Optional[str]) -> bool:
|
|||
return value.lower() in ("true", "1", "t", "y", "yes")
|
||||
|
||||
|
||||
|
||||
def _get_prisma_env() -> dict:
|
||||
"""Get environment variables for Prisma, handling offline mode if configured."""
|
||||
prisma_env = os.environ.copy()
|
||||
if str_to_bool(os.getenv("PRISMA_OFFLINE_MODE")):
|
||||
# These env vars prevent Prisma from attempting downloads
|
||||
prisma_env["NPM_CONFIG_PREFER_OFFLINE"] = "true"
|
||||
prisma_env["NPM_CONFIG_CACHE"] = os.getenv("NPM_CONFIG_CACHE", "/app/.cache/npm")
|
||||
prisma_env["NPM_CONFIG_CACHE"] = os.getenv(
|
||||
"NPM_CONFIG_CACHE", "/app/.cache/npm"
|
||||
)
|
||||
return prisma_env
|
||||
|
||||
|
||||
|
|
@ -34,29 +35,28 @@ def _get_prisma_command() -> str:
|
|||
if str_to_bool(os.getenv("PRISMA_OFFLINE_MODE")):
|
||||
# Primary location where Prisma Python package installs the CLI
|
||||
default_cli_path = "/app/.cache/prisma-python/binaries/node_modules/.bin/prisma"
|
||||
|
||||
|
||||
# Check if custom path is provided (for flexibility)
|
||||
custom_cli_path = os.getenv("PRISMA_CLI_PATH")
|
||||
if custom_cli_path and os.path.exists(custom_cli_path):
|
||||
logger.info(f"Using custom Prisma CLI at {custom_cli_path}")
|
||||
return custom_cli_path
|
||||
|
||||
|
||||
# Check the default location
|
||||
if os.path.exists(default_cli_path):
|
||||
logger.info(f"Using cached Prisma CLI at {default_cli_path}")
|
||||
return default_cli_path
|
||||
|
||||
|
||||
# If not found, log warning and fall back
|
||||
logger.warning(
|
||||
f"Prisma CLI not found at {default_cli_path}. "
|
||||
"Falling back to Python wrapper (may attempt downloads)"
|
||||
)
|
||||
|
||||
|
||||
# Fall back to the Python wrapper (will work in online mode)
|
||||
return "prisma"
|
||||
|
||||
|
||||
|
||||
class ProxyExtrasDBManager:
|
||||
@staticmethod
|
||||
def _get_prisma_dir() -> str:
|
||||
|
|
@ -119,7 +119,7 @@ class ProxyExtrasDBManager:
|
|||
stdout=open(migration_file, "w"),
|
||||
check=True,
|
||||
timeout=30,
|
||||
env=prisma_env
|
||||
env=prisma_env,
|
||||
)
|
||||
|
||||
# 3. Mark the migration as applied since it represents current state
|
||||
|
|
@ -134,7 +134,7 @@ class ProxyExtrasDBManager:
|
|||
],
|
||||
check=True,
|
||||
timeout=30,
|
||||
env=prisma_env
|
||||
env=prisma_env,
|
||||
)
|
||||
|
||||
return True
|
||||
|
|
@ -159,14 +159,20 @@ class ProxyExtrasDBManager:
|
|||
@staticmethod
|
||||
def _roll_back_migration(migration_name: str):
|
||||
"""Mark a specific migration as rolled back"""
|
||||
# Set up environment for offline mode if configured
|
||||
# Set up environment for offline mode if configured
|
||||
prisma_env = _get_prisma_env()
|
||||
subprocess.run(
|
||||
[_get_prisma_command(), "migrate", "resolve", "--rolled-back", migration_name],
|
||||
[
|
||||
_get_prisma_command(),
|
||||
"migrate",
|
||||
"resolve",
|
||||
"--rolled-back",
|
||||
migration_name,
|
||||
],
|
||||
timeout=60,
|
||||
check=True,
|
||||
capture_output=True,
|
||||
env=prisma_env
|
||||
env=prisma_env,
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
|
|
@ -178,7 +184,7 @@ class ProxyExtrasDBManager:
|
|||
timeout=60,
|
||||
check=True,
|
||||
capture_output=True,
|
||||
env=prisma_env
|
||||
env=prisma_env,
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
|
|
@ -228,6 +234,8 @@ class ProxyExtrasDBManager:
|
|||
r"duplicate key value violates",
|
||||
r"relation .* already exists",
|
||||
r"constraint .* already exists",
|
||||
r"does not exist",
|
||||
r"Can't drop database.* because it doesn't exist",
|
||||
]
|
||||
|
||||
for pattern in idempotent_patterns:
|
||||
|
|
@ -248,7 +256,7 @@ class ProxyExtrasDBManager:
|
|||
if not database_url:
|
||||
logger.error("DATABASE_URL not set")
|
||||
return
|
||||
|
||||
|
||||
diff_dir = (
|
||||
Path(migrations_dir)
|
||||
/ "migrations"
|
||||
|
|
@ -283,7 +291,7 @@ class ProxyExtrasDBManager:
|
|||
check=True,
|
||||
timeout=60,
|
||||
stdout=f,
|
||||
env=_get_prisma_env()
|
||||
env=_get_prisma_env(),
|
||||
)
|
||||
except subprocess.CalledProcessError as e:
|
||||
logger.warning(f"Failed to generate migration diff: {e.stderr}")
|
||||
|
|
@ -313,7 +321,7 @@ class ProxyExtrasDBManager:
|
|||
check=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
env=_get_prisma_env()
|
||||
env=_get_prisma_env(),
|
||||
)
|
||||
logger.info(f"prisma db execute stdout: {result.stdout}")
|
||||
logger.info("✅ Migration diff applied successfully")
|
||||
|
|
@ -331,12 +339,18 @@ class ProxyExtrasDBManager:
|
|||
try:
|
||||
logger.info(f"Resolving migration: {migration_name}")
|
||||
subprocess.run(
|
||||
[_get_prisma_command(), "migrate", "resolve", "--applied", migration_name],
|
||||
[
|
||||
_get_prisma_command(),
|
||||
"migrate",
|
||||
"resolve",
|
||||
"--applied",
|
||||
migration_name,
|
||||
],
|
||||
timeout=60,
|
||||
check=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
env=_get_prisma_env()
|
||||
env=_get_prisma_env(),
|
||||
)
|
||||
logger.debug(f"Resolved migration: {migration_name}")
|
||||
except subprocess.CalledProcessError as e:
|
||||
|
|
@ -375,7 +389,7 @@ class ProxyExtrasDBManager:
|
|||
check=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
env=_get_prisma_env()
|
||||
env=_get_prisma_env(),
|
||||
)
|
||||
logger.info(f"prisma migrate deploy stdout: {result.stdout}")
|
||||
|
||||
|
|
@ -397,27 +411,42 @@ class ProxyExtrasDBManager:
|
|||
)
|
||||
if migration_match:
|
||||
failed_migration = migration_match.group(1)
|
||||
logger.info(
|
||||
f"Found failed migration: {failed_migration}, marking as rolled back"
|
||||
)
|
||||
# Mark the failed migration as rolled back
|
||||
subprocess.run(
|
||||
[
|
||||
_get_prisma_command(),
|
||||
"migrate",
|
||||
"resolve",
|
||||
"--rolled-back",
|
||||
failed_migration,
|
||||
],
|
||||
timeout=60,
|
||||
check=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
env=_get_prisma_env()
|
||||
)
|
||||
logger.info(
|
||||
f"✅ Migration {failed_migration} marked as rolled back... retrying"
|
||||
)
|
||||
if ProxyExtrasDBManager._is_idempotent_error(e.stderr):
|
||||
logger.info(
|
||||
f"Migration {failed_migration} failed due to idempotent error (e.g., column already exists), resolving as applied"
|
||||
)
|
||||
ProxyExtrasDBManager._roll_back_migration(
|
||||
failed_migration
|
||||
)
|
||||
ProxyExtrasDBManager._resolve_specific_migration(
|
||||
failed_migration
|
||||
)
|
||||
logger.info(
|
||||
f"✅ Migration {failed_migration} resolved."
|
||||
)
|
||||
return True
|
||||
else:
|
||||
logger.info(
|
||||
f"Found failed migration: {failed_migration}, marking as rolled back"
|
||||
)
|
||||
# Mark the failed migration as rolled back
|
||||
subprocess.run(
|
||||
[
|
||||
_get_prisma_command(),
|
||||
"migrate",
|
||||
"resolve",
|
||||
"--rolled-back",
|
||||
failed_migration,
|
||||
],
|
||||
timeout=60,
|
||||
check=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
env=_get_prisma_env(),
|
||||
)
|
||||
logger.info(
|
||||
f"✅ Migration {failed_migration} marked as rolled back... retrying"
|
||||
)
|
||||
elif (
|
||||
"P3005" in e.stderr
|
||||
and "database schema is not empty" in e.stderr
|
||||
|
|
|
|||
|
|
@ -80,6 +80,8 @@ import dotenv
|
|||
litellm_mode = os.getenv("LITELLM_MODE", "DEV") # "PRODUCTION", "DEV"
|
||||
if litellm_mode == "DEV":
|
||||
dotenv.load_dotenv()
|
||||
|
||||
|
||||
####################################################
|
||||
if set_verbose:
|
||||
_turn_on_debug()
|
||||
|
|
|
|||
97
litellm/a2a_protocol/card_resolver.py
Normal file
97
litellm/a2a_protocol/card_resolver.py
Normal file
|
|
@ -0,0 +1,97 @@
|
|||
"""
|
||||
Custom A2A Card Resolver for LiteLLM.
|
||||
|
||||
Extends the A2A SDK's card resolver to support multiple well-known paths.
|
||||
"""
|
||||
|
||||
from typing import TYPE_CHECKING, Any, Dict, Optional
|
||||
|
||||
from litellm._logging import verbose_logger
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from a2a.types import AgentCard
|
||||
|
||||
# Runtime imports with availability check
|
||||
_A2ACardResolver: Any = None
|
||||
AGENT_CARD_WELL_KNOWN_PATH: str = "/.well-known/agent-card.json"
|
||||
PREV_AGENT_CARD_WELL_KNOWN_PATH: str = "/.well-known/agent.json"
|
||||
|
||||
try:
|
||||
from a2a.client import A2ACardResolver as _A2ACardResolver # type: ignore[no-redef]
|
||||
from a2a.utils.constants import ( # type: ignore[no-redef]
|
||||
AGENT_CARD_WELL_KNOWN_PATH,
|
||||
PREV_AGENT_CARD_WELL_KNOWN_PATH,
|
||||
)
|
||||
except ImportError:
|
||||
pass
|
||||
|
||||
|
||||
class LiteLLMA2ACardResolver(_A2ACardResolver): # type: ignore[misc]
|
||||
"""
|
||||
Custom A2A card resolver that supports multiple well-known paths.
|
||||
|
||||
Extends the base A2ACardResolver to try both:
|
||||
- /.well-known/agent-card.json (standard)
|
||||
- /.well-known/agent.json (previous/alternative)
|
||||
"""
|
||||
|
||||
async def get_agent_card(
|
||||
self,
|
||||
relative_card_path: Optional[str] = None,
|
||||
http_kwargs: Optional[Dict[str, Any]] = None,
|
||||
) -> "AgentCard":
|
||||
"""
|
||||
Fetch the agent card, trying multiple well-known paths.
|
||||
|
||||
First tries the standard path, then falls back to the previous path.
|
||||
|
||||
Args:
|
||||
relative_card_path: Optional path to the agent card endpoint.
|
||||
If None, tries both well-known paths.
|
||||
http_kwargs: Optional dictionary of keyword arguments to pass to httpx.get
|
||||
|
||||
Returns:
|
||||
AgentCard from the A2A agent
|
||||
|
||||
Raises:
|
||||
A2AClientHTTPError or A2AClientJSONError if both paths fail
|
||||
"""
|
||||
# If a specific path is provided, use the parent implementation
|
||||
if relative_card_path is not None:
|
||||
return await super().get_agent_card(
|
||||
relative_card_path=relative_card_path,
|
||||
http_kwargs=http_kwargs,
|
||||
)
|
||||
|
||||
# Try both well-known paths
|
||||
paths = [
|
||||
AGENT_CARD_WELL_KNOWN_PATH,
|
||||
PREV_AGENT_CARD_WELL_KNOWN_PATH,
|
||||
]
|
||||
|
||||
last_error = None
|
||||
for path in paths:
|
||||
try:
|
||||
verbose_logger.debug(
|
||||
f"Attempting to fetch agent card from {self.base_url}{path}"
|
||||
)
|
||||
return await super().get_agent_card(
|
||||
relative_card_path=path,
|
||||
http_kwargs=http_kwargs,
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_logger.debug(
|
||||
f"Failed to fetch agent card from {self.base_url}{path}: {e}"
|
||||
)
|
||||
last_error = e
|
||||
continue
|
||||
|
||||
# If we get here, all paths failed - re-raise the last error
|
||||
if last_error is not None:
|
||||
raise last_error
|
||||
|
||||
# This shouldn't happen, but just in case
|
||||
raise Exception(
|
||||
f"Failed to fetch agent card from {self.base_url}. "
|
||||
f"Tried paths: {', '.join(paths)}"
|
||||
)
|
||||
|
|
@ -6,6 +6,7 @@ Provides standalone functions with @client decorator for LiteLLM logging integra
|
|||
|
||||
import asyncio
|
||||
import datetime
|
||||
import uuid
|
||||
from typing import TYPE_CHECKING, Any, AsyncIterator, Coroutine, Dict, Optional, Union
|
||||
|
||||
import litellm
|
||||
|
|
@ -20,7 +21,6 @@ from litellm.llms.custom_httpx.http_handler import (
|
|||
)
|
||||
from litellm.types.agents import LiteLLMSendMessageResponse
|
||||
from litellm.utils import client
|
||||
import uuid
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from a2a.client import A2AClient as A2AClientType
|
||||
|
|
@ -36,13 +36,18 @@ A2ACardResolver: Any = None
|
|||
_A2AClient: Any = None
|
||||
|
||||
try:
|
||||
from a2a.client import A2ACardResolver # type: ignore[no-redef]
|
||||
from a2a.client import A2AClient as _A2AClient # type: ignore[no-redef]
|
||||
|
||||
A2A_SDK_AVAILABLE = True
|
||||
except ImportError:
|
||||
pass
|
||||
|
||||
# Import our custom card resolver that supports multiple well-known paths
|
||||
from litellm.a2a_protocol.card_resolver import LiteLLMA2ACardResolver
|
||||
|
||||
# Use our custom resolver instead of the default A2A SDK resolver
|
||||
A2ACardResolver = LiteLLMA2ACardResolver
|
||||
|
||||
|
||||
def _set_usage_on_logging_obj(
|
||||
kwargs: Dict[str, Any],
|
||||
|
|
|
|||
|
|
@ -1165,7 +1165,12 @@ LITELLM_CLI_SOURCE_IDENTIFIER = "litellm-cli"
|
|||
LITELLM_CLI_SESSION_TOKEN_PREFIX = "litellm-session-token"
|
||||
CLI_SSO_SESSION_CACHE_KEY_PREFIX = "cli_sso_session"
|
||||
CLI_JWT_TOKEN_NAME = "cli-jwt-token"
|
||||
CLI_JWT_EXPIRATION_HOURS = int(os.getenv("LITELLM_CLI_JWT_EXPIRATION_HOURS", 24))
|
||||
# Support both CLI_JWT_EXPIRATION_HOURS and LITELLM_CLI_JWT_EXPIRATION_HOURS for backwards compatibility
|
||||
CLI_JWT_EXPIRATION_HOURS = int(
|
||||
os.getenv("CLI_JWT_EXPIRATION_HOURS")
|
||||
or os.getenv("LITELLM_CLI_JWT_EXPIRATION_HOURS")
|
||||
or 24
|
||||
)
|
||||
|
||||
########################### DB CRON JOB NAMES ###########################
|
||||
DB_SPEND_UPDATE_JOB_NAME = "db_spend_update_job"
|
||||
|
|
|
|||
|
|
@ -23,7 +23,11 @@ from litellm.litellm_core_utils.llm_cost_calc.usage_object_transformation import
|
|||
from litellm.litellm_core_utils.llm_cost_calc.utils import (
|
||||
CostCalculatorUtils,
|
||||
_generic_cost_per_character,
|
||||
_get_service_tier_cost_key,
|
||||
_parse_prompt_tokens_details,
|
||||
calculate_cost_component,
|
||||
generic_cost_per_token,
|
||||
get_billable_input_tokens,
|
||||
select_cost_metric_for_model,
|
||||
)
|
||||
from litellm.llms.anthropic.cost_calculation import (
|
||||
|
|
@ -431,12 +435,18 @@ def cost_per_token( # noqa: PLR0915
|
|||
model=model, custom_llm_provider=custom_llm_provider
|
||||
)
|
||||
|
||||
if model_info["input_cost_per_token"] > 0:
|
||||
## COST PER TOKEN ##
|
||||
prompt_tokens_cost_usd_dollar = (
|
||||
model_info["input_cost_per_token"] * prompt_tokens
|
||||
if (
|
||||
model_info.get("input_cost_per_token", 0) > 0
|
||||
or model_info.get("output_cost_per_token", 0) > 0
|
||||
):
|
||||
return generic_cost_per_token(
|
||||
model=model,
|
||||
usage=usage_block,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
service_tier=service_tier,
|
||||
)
|
||||
elif (
|
||||
|
||||
if (
|
||||
model_info.get("input_cost_per_second", None) is not None
|
||||
and response_time_ms is not None
|
||||
):
|
||||
|
|
@ -451,11 +461,7 @@ def cost_per_token( # noqa: PLR0915
|
|||
model_info["input_cost_per_second"] * response_time_ms / 1000 # type: ignore
|
||||
)
|
||||
|
||||
if model_info["output_cost_per_token"] > 0:
|
||||
completion_tokens_cost_usd_dollar = (
|
||||
model_info["output_cost_per_token"] * completion_tokens
|
||||
)
|
||||
elif (
|
||||
if (
|
||||
model_info.get("output_cost_per_second", None) is not None
|
||||
and response_time_ms is not None
|
||||
):
|
||||
|
|
@ -955,7 +961,10 @@ def completion_cost( # noqa: PLR0915
|
|||
router_model_id=router_model_id,
|
||||
)
|
||||
|
||||
potential_model_names = [selected_model, _get_response_model(completion_response)]
|
||||
potential_model_names = [
|
||||
selected_model,
|
||||
_get_response_model(completion_response),
|
||||
]
|
||||
if model is not None:
|
||||
potential_model_names.append(model)
|
||||
|
||||
|
|
@ -1710,10 +1719,16 @@ def default_image_cost_calculator(
|
|||
)
|
||||
|
||||
# Priority 1: Use per-image pricing if available (for gpt-image-1 and similar models)
|
||||
if "input_cost_per_image" in cost_info and cost_info["input_cost_per_image"] is not None:
|
||||
if (
|
||||
"input_cost_per_image" in cost_info
|
||||
and cost_info["input_cost_per_image"] is not None
|
||||
):
|
||||
return cost_info["input_cost_per_image"] * n
|
||||
# Priority 2: Fall back to per-pixel pricing for backward compatibility
|
||||
elif "input_cost_per_pixel" in cost_info and cost_info["input_cost_per_pixel"] is not None:
|
||||
elif (
|
||||
"input_cost_per_pixel" in cost_info
|
||||
and cost_info["input_cost_per_pixel"] is not None
|
||||
):
|
||||
return cost_info["input_cost_per_pixel"] * height * width * n
|
||||
else:
|
||||
raise Exception(
|
||||
|
|
@ -1833,9 +1848,22 @@ def batch_cost_calculator(
|
|||
if input_cost_per_token_batches:
|
||||
total_prompt_cost = usage.prompt_tokens * input_cost_per_token_batches
|
||||
elif input_cost_per_token:
|
||||
# Subtract cached tokens from prompt_tokens before calculating cost
|
||||
# Fixes issue where cached tokens are being charged again
|
||||
total_prompt_cost = (
|
||||
usage.prompt_tokens * (input_cost_per_token) / 2
|
||||
get_billable_input_tokens(usage) * (input_cost_per_token) / 2
|
||||
) # batch cost is usually half of the regular token cost
|
||||
|
||||
# Add cache read cost if applicable
|
||||
details = _parse_prompt_tokens_details(usage)
|
||||
cache_read_tokens = details["cache_hit_tokens"]
|
||||
cache_read_cost_key = _get_service_tier_cost_key(
|
||||
"cache_read_input_token_cost", None
|
||||
)
|
||||
total_prompt_cost += (
|
||||
calculate_cost_component(model_info, cache_read_cost_key, cache_read_tokens)
|
||||
/ 2
|
||||
)
|
||||
if output_cost_per_token_batches:
|
||||
total_completion_cost = usage.completion_tokens * output_cost_per_token_batches
|
||||
elif output_cost_per_token:
|
||||
|
|
|
|||
|
|
@ -300,43 +300,59 @@ class LangfusePromptManagement(LangFuseLogger, PromptManagementBase, CustomLogge
|
|||
)
|
||||
|
||||
async def async_log_success_event(self, kwargs, response_obj, start_time, end_time):
|
||||
standard_callback_dynamic_params = kwargs.get(
|
||||
"standard_callback_dynamic_params"
|
||||
)
|
||||
langfuse_logger_to_use = LangFuseHandler.get_langfuse_logger_for_request(
|
||||
globalLangfuseLogger=self,
|
||||
standard_callback_dynamic_params=standard_callback_dynamic_params,
|
||||
in_memory_dynamic_logger_cache=in_memory_dynamic_logger_cache,
|
||||
)
|
||||
langfuse_logger_to_use.log_event_on_langfuse(
|
||||
kwargs=kwargs,
|
||||
response_obj=response_obj,
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
user_id=kwargs.get("user", None),
|
||||
)
|
||||
try:
|
||||
standard_callback_dynamic_params = kwargs.get(
|
||||
"standard_callback_dynamic_params"
|
||||
)
|
||||
langfuse_logger_to_use = LangFuseHandler.get_langfuse_logger_for_request(
|
||||
globalLangfuseLogger=self,
|
||||
standard_callback_dynamic_params=standard_callback_dynamic_params,
|
||||
in_memory_dynamic_logger_cache=in_memory_dynamic_logger_cache,
|
||||
)
|
||||
langfuse_logger_to_use.log_event_on_langfuse(
|
||||
kwargs=kwargs,
|
||||
response_obj=response_obj,
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
user_id=kwargs.get("user", None),
|
||||
)
|
||||
except Exception as e:
|
||||
from litellm._logging import verbose_logger
|
||||
|
||||
verbose_logger.exception(
|
||||
f"Langfuse Layer Error - Exception occurred while logging success event: {str(e)}"
|
||||
)
|
||||
self.handle_callback_failure(callback_name="langfuse")
|
||||
|
||||
async def async_log_failure_event(self, kwargs, response_obj, start_time, end_time):
|
||||
standard_callback_dynamic_params = kwargs.get(
|
||||
"standard_callback_dynamic_params"
|
||||
)
|
||||
langfuse_logger_to_use = LangFuseHandler.get_langfuse_logger_for_request(
|
||||
globalLangfuseLogger=self,
|
||||
standard_callback_dynamic_params=standard_callback_dynamic_params,
|
||||
in_memory_dynamic_logger_cache=in_memory_dynamic_logger_cache,
|
||||
)
|
||||
standard_logging_object = cast(
|
||||
Optional[StandardLoggingPayload],
|
||||
kwargs.get("standard_logging_object", None),
|
||||
)
|
||||
if standard_logging_object is None:
|
||||
return
|
||||
langfuse_logger_to_use.log_event_on_langfuse(
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
response_obj=None,
|
||||
user_id=kwargs.get("user", None),
|
||||
status_message=standard_logging_object["error_str"],
|
||||
level="ERROR",
|
||||
kwargs=kwargs,
|
||||
)
|
||||
try:
|
||||
standard_callback_dynamic_params = kwargs.get(
|
||||
"standard_callback_dynamic_params"
|
||||
)
|
||||
langfuse_logger_to_use = LangFuseHandler.get_langfuse_logger_for_request(
|
||||
globalLangfuseLogger=self,
|
||||
standard_callback_dynamic_params=standard_callback_dynamic_params,
|
||||
in_memory_dynamic_logger_cache=in_memory_dynamic_logger_cache,
|
||||
)
|
||||
standard_logging_object = cast(
|
||||
Optional[StandardLoggingPayload],
|
||||
kwargs.get("standard_logging_object", None),
|
||||
)
|
||||
if standard_logging_object is None:
|
||||
return
|
||||
langfuse_logger_to_use.log_event_on_langfuse(
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
response_obj=None,
|
||||
user_id=kwargs.get("user", None),
|
||||
status_message=standard_logging_object["error_str"],
|
||||
level="ERROR",
|
||||
kwargs=kwargs,
|
||||
)
|
||||
except Exception as e:
|
||||
from litellm._logging import verbose_logger
|
||||
|
||||
verbose_logger.exception(
|
||||
f"Langfuse Layer Error - Exception occurred while logging failure event: {str(e)}"
|
||||
)
|
||||
self.handle_callback_failure(callback_name="langfuse")
|
||||
|
|
|
|||
|
|
@ -144,6 +144,7 @@ class OpenTelemetry(CustomLogger):
|
|||
self.OTEL_EXPORTER = self.config.exporter
|
||||
self.OTEL_ENDPOINT = self.config.endpoint
|
||||
self.OTEL_HEADERS = self.config.headers
|
||||
self._tracer_provider_cache: Dict[str, Any] = {}
|
||||
self._init_tracing(tracer_provider)
|
||||
|
||||
_debug_otel = str(os.getenv("DEBUG_OTEL", "False")).lower()
|
||||
|
|
@ -615,12 +616,20 @@ class OpenTelemetry(CustomLogger):
|
|||
"""Create a temporary tracer with dynamic headers for this request only."""
|
||||
from opentelemetry.sdk.trace import TracerProvider
|
||||
|
||||
# Prevents thread exhaustion by reusing providers for the same credential sets (e.g. per-team keys)
|
||||
cache_key = str(sorted(dynamic_headers.items()))
|
||||
if cache_key in self._tracer_provider_cache:
|
||||
return self._tracer_provider_cache[cache_key].get_tracer(LITELLM_TRACER_NAME)
|
||||
|
||||
# Create a temporary tracer provider with dynamic headers
|
||||
temp_provider = TracerProvider(resource=self._get_litellm_resource(self.config))
|
||||
temp_provider.add_span_processor(
|
||||
self._get_span_processor(dynamic_headers=dynamic_headers)
|
||||
)
|
||||
|
||||
# Store in cache for reuse
|
||||
self._tracer_provider_cache[cache_key] = temp_provider
|
||||
|
||||
return temp_provider.get_tracer(LITELLM_TRACER_NAME)
|
||||
|
||||
def construct_dynamic_otel_headers(
|
||||
|
|
@ -995,9 +1004,13 @@ class OpenTelemetry(CustomLogger):
|
|||
|
||||
from opentelemetry._logs import SeverityNumber, get_logger, get_logger_provider
|
||||
try:
|
||||
from opentelemetry.sdk._logs import LogRecord as SdkLogRecord # type: ignore[attr-defined] # OTEL < 1.39.0
|
||||
from opentelemetry.sdk._logs import (
|
||||
LogRecord as SdkLogRecord, # type: ignore[attr-defined] # OTEL < 1.39.0
|
||||
)
|
||||
except ImportError:
|
||||
from opentelemetry.sdk._logs._internal import LogRecord as SdkLogRecord # OTEL >= 1.39.0
|
||||
from opentelemetry.sdk._logs._internal import (
|
||||
LogRecord as SdkLogRecord, # OTEL >= 1.39.0
|
||||
)
|
||||
|
||||
otel_logger = get_logger(LITELLM_LOGGER_NAME)
|
||||
|
||||
|
|
@ -1618,6 +1631,7 @@ class OpenTelemetry(CustomLogger):
|
|||
)
|
||||
|
||||
except Exception as e:
|
||||
self.handle_callback_failure(callback_name= self.callback_name)
|
||||
verbose_logger.exception(
|
||||
"OpenTelemetry logging error in set_attributes %s", str(e)
|
||||
)
|
||||
|
|
|
|||
|
|
@ -901,7 +901,7 @@ class PrometheusLogger(CustomLogger):
|
|||
|
||||
model = kwargs.get("model", "")
|
||||
litellm_params = kwargs.get("litellm_params", {}) or {}
|
||||
_metadata = litellm_params.get("metadata", {})
|
||||
_metadata = litellm_params.get("metadata") or {}
|
||||
get_end_user_id_for_cost_tracking = _get_cached_end_user_id_for_cost_tracking()
|
||||
|
||||
end_user_id = get_end_user_id_for_cost_tracking(
|
||||
|
|
@ -1178,26 +1178,15 @@ class PrometheusLogger(CustomLogger):
|
|||
response_cost: float,
|
||||
user_id: Optional[str] = None,
|
||||
):
|
||||
_team_spend = litellm_params.get("metadata", {}).get(
|
||||
"user_api_key_team_spend", None
|
||||
)
|
||||
_team_max_budget = litellm_params.get("metadata", {}).get(
|
||||
"user_api_key_team_max_budget", None
|
||||
)
|
||||
_metadata = litellm_params.get("metadata") or {}
|
||||
_team_spend = _metadata.get("user_api_key_team_spend", None)
|
||||
_team_max_budget = _metadata.get("user_api_key_team_max_budget", None)
|
||||
|
||||
_api_key_spend = litellm_params.get("metadata", {}).get(
|
||||
"user_api_key_spend", None
|
||||
)
|
||||
_api_key_max_budget = litellm_params.get("metadata", {}).get(
|
||||
"user_api_key_max_budget", None
|
||||
)
|
||||
_api_key_spend = _metadata.get("user_api_key_spend", None)
|
||||
_api_key_max_budget = _metadata.get("user_api_key_max_budget", None)
|
||||
|
||||
_user_spend = litellm_params.get("metadata", {}).get(
|
||||
"user_api_key_user_spend", None
|
||||
)
|
||||
_user_max_budget = litellm_params.get("metadata", {}).get(
|
||||
"user_api_key_user_max_budget", None
|
||||
)
|
||||
_user_spend = _metadata.get("user_api_key_user_spend", None)
|
||||
_user_max_budget = _metadata.get("user_api_key_user_max_budget", None)
|
||||
|
||||
await self._set_api_key_budget_metrics_after_api_request(
|
||||
user_api_key=user_api_key,
|
||||
|
|
@ -1310,12 +1299,14 @@ class PrometheusLogger(CustomLogger):
|
|||
time_to_first_token_seconds is not None
|
||||
and kwargs.get("stream", False) is True # only emit for streaming requests
|
||||
):
|
||||
_ttft_labels = prometheus_label_factory(
|
||||
supported_enum_labels=self.get_labels_for_metric(
|
||||
metric_name="litellm_llm_api_time_to_first_token_metric"
|
||||
),
|
||||
enum_values=enum_values,
|
||||
)
|
||||
self.litellm_llm_api_time_to_first_token_metric.labels(
|
||||
model,
|
||||
user_api_key,
|
||||
user_api_key_alias,
|
||||
user_api_team,
|
||||
user_api_team_alias,
|
||||
**_ttft_labels
|
||||
).observe(time_to_first_token_seconds)
|
||||
else:
|
||||
verbose_logger.debug(
|
||||
|
|
@ -1355,7 +1346,7 @@ class PrometheusLogger(CustomLogger):
|
|||
|
||||
# request queue time (time from arrival to processing start)
|
||||
_litellm_params = kwargs.get("litellm_params", {}) or {}
|
||||
queue_time_seconds = _litellm_params.get("metadata", {}).get(
|
||||
queue_time_seconds = (_litellm_params.get("metadata") or {}).get(
|
||||
"queue_time_seconds"
|
||||
)
|
||||
if queue_time_seconds is not None and queue_time_seconds >= 0:
|
||||
|
|
@ -2509,8 +2500,8 @@ class PrometheusLogger(CustomLogger):
|
|||
self,
|
||||
user_api_team: Optional[str],
|
||||
user_api_team_alias: Optional[str],
|
||||
team_spend: float,
|
||||
team_max_budget: float,
|
||||
team_spend: Optional[float],
|
||||
team_max_budget: Optional[float],
|
||||
response_cost: float,
|
||||
):
|
||||
"""
|
||||
|
|
@ -2672,7 +2663,7 @@ class PrometheusLogger(CustomLogger):
|
|||
user_api_key: Optional[str],
|
||||
user_api_key_alias: Optional[str],
|
||||
response_cost: float,
|
||||
key_max_budget: float,
|
||||
key_max_budget: Optional[float],
|
||||
key_spend: Optional[float],
|
||||
):
|
||||
if user_api_key:
|
||||
|
|
@ -2689,7 +2680,7 @@ class PrometheusLogger(CustomLogger):
|
|||
self,
|
||||
user_api_key: str,
|
||||
user_api_key_alias: str,
|
||||
key_max_budget: float,
|
||||
key_max_budget: Optional[float],
|
||||
key_spend: Optional[float],
|
||||
response_cost: float,
|
||||
) -> UserAPIKeyAuth:
|
||||
|
|
|
|||
|
|
@ -1638,11 +1638,19 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
"standard_logging_object"
|
||||
)
|
||||
) is not None:
|
||||
standard_logging_payload["response"] = (
|
||||
response_dict = (
|
||||
result.model_dump()
|
||||
if hasattr(result, "model_dump")
|
||||
else dict(result)
|
||||
)
|
||||
# Ensure usage is properly included with transformed chat format
|
||||
if transformed_usage is not None:
|
||||
response_dict["usage"] = (
|
||||
transformed_usage.model_dump()
|
||||
if hasattr(transformed_usage, "model_dump")
|
||||
else dict(transformed_usage)
|
||||
)
|
||||
standard_logging_payload["response"] = response_dict
|
||||
elif isinstance(result, TranscriptionResponse):
|
||||
from litellm.litellm_core_utils.llm_cost_calc.usage_object_transformation import (
|
||||
TranscriptionUsageObjectTransformation,
|
||||
|
|
@ -4540,6 +4548,10 @@ class StandardLoggingPayloadSetup:
|
|||
)
|
||||
elif isinstance(usage, Usage):
|
||||
return usage
|
||||
elif isinstance(usage, ResponseAPIUsage):
|
||||
return ResponseAPILoggingUtils._transform_response_api_usage_to_chat_usage(
|
||||
usage
|
||||
)
|
||||
elif isinstance(usage, dict):
|
||||
if ResponseAPILoggingUtils._is_response_api_usage(usage):
|
||||
return (
|
||||
|
|
|
|||
|
|
@ -23,6 +23,15 @@ def _is_above_128k(tokens: float) -> bool:
|
|||
return False
|
||||
|
||||
|
||||
def get_billable_input_tokens(usage: Usage) -> int:
|
||||
"""
|
||||
Returns the number of billable input tokens.
|
||||
Subtracts cached tokens from prompt tokens if applicable.
|
||||
"""
|
||||
details = _parse_prompt_tokens_details(usage)
|
||||
return usage.prompt_tokens - details["cache_hit_tokens"]
|
||||
|
||||
|
||||
def select_cost_metric_for_model(
|
||||
model_info: ModelInfo,
|
||||
) -> Literal["cost_per_character", "cost_per_token"]:
|
||||
|
|
@ -190,7 +199,6 @@ def _get_token_base_cost(
|
|||
1000 if "k" in threshold_str else 1
|
||||
)
|
||||
if usage.prompt_tokens > threshold:
|
||||
|
||||
prompt_base_cost = cast(
|
||||
float, _get_cost_per_unit(model_info, key, prompt_base_cost)
|
||||
)
|
||||
|
|
@ -566,14 +574,28 @@ def generic_cost_per_token( # noqa: PLR0915
|
|||
if usage.prompt_tokens_details:
|
||||
prompt_tokens_details = _parse_prompt_tokens_details(usage)
|
||||
|
||||
## EDGE CASE - text tokens not set inside PromptTokensDetails
|
||||
## EDGE CASE - text tokens not set or includes cached tokens (double-counting)
|
||||
## Some providers (like xAI) report text_tokens = prompt_tokens (including cached)
|
||||
## We detect this when: text_tokens + cached_tokens + other > prompt_tokens
|
||||
## Ref: https://github.com/BerriAI/litellm/issues/19680, #14874, #14875
|
||||
|
||||
if prompt_tokens_details["text_tokens"] == 0:
|
||||
cache_hit = prompt_tokens_details["cache_hit_tokens"]
|
||||
text_tokens = prompt_tokens_details["text_tokens"]
|
||||
audio_tokens = prompt_tokens_details["audio_tokens"]
|
||||
cache_creation = prompt_tokens_details["cache_creation_tokens"]
|
||||
image_tokens = prompt_tokens_details["image_tokens"]
|
||||
|
||||
# Check for double-counting: sum of details > prompt_tokens means overlap
|
||||
total_details = text_tokens + cache_hit + audio_tokens + cache_creation + image_tokens
|
||||
has_double_counting = cache_hit > 0 and total_details > usage.prompt_tokens
|
||||
|
||||
if text_tokens == 0 or has_double_counting:
|
||||
text_tokens = (
|
||||
usage.prompt_tokens
|
||||
- prompt_tokens_details["cache_hit_tokens"]
|
||||
- prompt_tokens_details["audio_tokens"]
|
||||
- prompt_tokens_details["cache_creation_tokens"]
|
||||
- cache_hit
|
||||
- audio_tokens
|
||||
- cache_creation
|
||||
- image_tokens
|
||||
)
|
||||
prompt_tokens_details["text_tokens"] = text_tokens
|
||||
|
||||
|
|
@ -619,7 +641,11 @@ def generic_cost_per_token( # noqa: PLR0915
|
|||
# Calculate text tokens as remainder when we have a breakdown
|
||||
# This handles cases like OpenAI's reasoning models where text_tokens isn't provided
|
||||
text_tokens = max(
|
||||
0, usage.completion_tokens - reasoning_tokens - audio_tokens - image_tokens
|
||||
0,
|
||||
usage.completion_tokens
|
||||
- reasoning_tokens
|
||||
- audio_tokens
|
||||
- image_tokens,
|
||||
)
|
||||
else:
|
||||
# No breakdown at all, all tokens are text tokens
|
||||
|
|
|
|||
|
|
@ -415,6 +415,28 @@ class LoggingWorker:
|
|||
"""
|
||||
Safely log a message during shutdown, suppressing errors if logging is closed.
|
||||
"""
|
||||
# Check if logger has valid handlers before attempting to log
|
||||
# During shutdown, handlers may be closed, causing ValueError when writing
|
||||
if not hasattr(verbose_logger, 'handlers') or not verbose_logger.handlers:
|
||||
return
|
||||
|
||||
# Check if any handler has a valid stream
|
||||
has_valid_handler = False
|
||||
for handler in verbose_logger.handlers:
|
||||
try:
|
||||
if hasattr(handler, 'stream') and handler.stream and not handler.stream.closed:
|
||||
has_valid_handler = True
|
||||
break
|
||||
elif not hasattr(handler, 'stream'):
|
||||
# Non-stream handlers (like NullHandler) are always valid
|
||||
has_valid_handler = True
|
||||
break
|
||||
except (AttributeError, ValueError):
|
||||
continue
|
||||
|
||||
if not has_valid_handler:
|
||||
return
|
||||
|
||||
try:
|
||||
if level == "debug":
|
||||
verbose_logger.debug(message)
|
||||
|
|
|
|||
|
|
@ -1677,13 +1677,16 @@ def convert_to_anthropic_tool_result(
|
|||
] = []
|
||||
for content in content_list:
|
||||
if content["type"] == "text":
|
||||
anthropic_content_list.append(
|
||||
AnthropicMessagesToolResultContent(
|
||||
type="text",
|
||||
text=content["text"],
|
||||
cache_control=content.get("cache_control", None),
|
||||
)
|
||||
)
|
||||
# Only include cache_control if explicitly set and not None
|
||||
# to avoid sending "cache_control": null which breaks some API channels
|
||||
text_content: AnthropicMessagesToolResultContent = {
|
||||
"type": "text",
|
||||
"text": content["text"],
|
||||
}
|
||||
cache_control_value = content.get("cache_control")
|
||||
if cache_control_value is not None:
|
||||
text_content["cache_control"] = cache_control_value
|
||||
anthropic_content_list.append(text_content)
|
||||
elif content["type"] == "image_url":
|
||||
format = (
|
||||
content["image_url"].get("format")
|
||||
|
|
|
|||
|
|
@ -1378,7 +1378,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
else 0
|
||||
)
|
||||
completion_token_details = CompletionTokensDetailsWrapper(
|
||||
reasoning_tokens=reasoning_tokens if reasoning_tokens > 0 else None,
|
||||
reasoning_tokens=reasoning_tokens if reasoning_tokens > 0 else 0,
|
||||
text_tokens=completion_tokens - reasoning_tokens if reasoning_tokens > 0 else completion_tokens,
|
||||
)
|
||||
total_tokens = prompt_tokens + completion_tokens
|
||||
|
|
|
|||
|
|
@ -1,11 +1,12 @@
|
|||
"""
|
||||
Helper util for handling azure openai-specific cost calculation
|
||||
- e.g.: prompt caching
|
||||
- e.g.: prompt caching, audio tokens
|
||||
"""
|
||||
|
||||
from typing import Optional, Tuple
|
||||
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.litellm_core_utils.llm_cost_calc.utils import generic_cost_per_token
|
||||
from litellm.types.utils import Usage
|
||||
from litellm.utils import get_model_info
|
||||
|
||||
|
|
@ -18,34 +19,15 @@ def cost_per_token(
|
|||
|
||||
Input:
|
||||
- model: str, the model name without provider prefix
|
||||
- usage: LiteLLM Usage block, containing anthropic caching information
|
||||
- usage: LiteLLM Usage block, containing caching and audio token information
|
||||
|
||||
Returns:
|
||||
Tuple[float, float] - prompt_cost_in_usd, completion_cost_in_usd
|
||||
"""
|
||||
## GET MODEL INFO
|
||||
model_info = get_model_info(model=model, custom_llm_provider="azure")
|
||||
cached_tokens: Optional[int] = None
|
||||
## CALCULATE INPUT COST
|
||||
non_cached_text_tokens = usage.prompt_tokens
|
||||
if usage.prompt_tokens_details and usage.prompt_tokens_details.cached_tokens:
|
||||
cached_tokens = usage.prompt_tokens_details.cached_tokens
|
||||
non_cached_text_tokens = non_cached_text_tokens - cached_tokens
|
||||
prompt_cost: float = non_cached_text_tokens * model_info["input_cost_per_token"]
|
||||
|
||||
## CALCULATE OUTPUT COST
|
||||
completion_cost: float = (
|
||||
usage["completion_tokens"] * model_info["output_cost_per_token"]
|
||||
)
|
||||
|
||||
## Prompt Caching cost calculation
|
||||
if model_info.get("cache_read_input_token_cost") is not None and cached_tokens:
|
||||
# Note: We read ._cache_read_input_tokens from the Usage - since cost_calculator.py standardizes the cache read tokens on usage._cache_read_input_tokens
|
||||
prompt_cost += cached_tokens * (
|
||||
model_info.get("cache_read_input_token_cost", 0) or 0
|
||||
)
|
||||
|
||||
## Speech / Audio cost calculation
|
||||
## Speech / Audio cost calculation (cost per second for TTS models)
|
||||
if (
|
||||
"output_cost_per_second" in model_info
|
||||
and model_info["output_cost_per_second"] is not None
|
||||
|
|
@ -55,7 +37,14 @@ def cost_per_token(
|
|||
f"For model={model} - output_cost_per_second: {model_info.get('output_cost_per_second')}; response time: {response_time_ms}"
|
||||
)
|
||||
## COST PER SECOND ##
|
||||
prompt_cost = 0
|
||||
prompt_cost = 0.0
|
||||
completion_cost = model_info["output_cost_per_second"] * response_time_ms / 1000
|
||||
return prompt_cost, completion_cost
|
||||
|
||||
return prompt_cost, completion_cost
|
||||
## Use generic cost calculator for all other cases
|
||||
## This properly handles: text tokens, audio tokens, cached tokens, reasoning tokens, etc.
|
||||
return generic_cost_per_token(
|
||||
model=model,
|
||||
usage=usage,
|
||||
custom_llm_provider="azure",
|
||||
)
|
||||
|
|
|
|||
|
|
@ -31,6 +31,16 @@ else:
|
|||
GIGACHAT_BASE_URL = "https://gigachat.devices.sberbank.ru/api/v1"
|
||||
|
||||
|
||||
def is_valid_json(value: str) -> bool:
|
||||
"""Checks whether the value passed is a valid serialized JSON string"""
|
||||
try:
|
||||
json.loads(value)
|
||||
except json.JSONDecodeError:
|
||||
return False
|
||||
else:
|
||||
return True
|
||||
|
||||
|
||||
class GigaChatError(BaseLLMException):
|
||||
"""GigaChat API error."""
|
||||
|
||||
|
|
@ -101,7 +111,11 @@ class GigaChatConfig(BaseConfig):
|
|||
Set up headers with OAuth token.
|
||||
"""
|
||||
# Get access token
|
||||
credentials = api_key or get_secret_str("GIGACHAT_CREDENTIALS") or get_secret_str("GIGACHAT_API_KEY")
|
||||
credentials = (
|
||||
api_key
|
||||
or get_secret_str("GIGACHAT_CREDENTIALS")
|
||||
or get_secret_str("GIGACHAT_API_KEY")
|
||||
)
|
||||
access_token = get_access_token(credentials=credentials)
|
||||
|
||||
# Store credentials for image uploads
|
||||
|
|
@ -193,11 +207,13 @@ class GigaChatConfig(BaseConfig):
|
|||
for tool in tools:
|
||||
if tool.get("type") == "function":
|
||||
func = tool.get("function", {})
|
||||
functions.append({
|
||||
"name": func.get("name", ""),
|
||||
"description": func.get("description", ""),
|
||||
"parameters": func.get("parameters", {}),
|
||||
})
|
||||
functions.append(
|
||||
{
|
||||
"name": func.get("name", ""),
|
||||
"description": func.get("description", ""),
|
||||
"parameters": func.get("parameters", {}),
|
||||
}
|
||||
)
|
||||
return functions
|
||||
|
||||
def _map_tool_choice(
|
||||
|
|
@ -281,8 +297,14 @@ class GigaChatConfig(BaseConfig):
|
|||
}
|
||||
|
||||
# Add optional params
|
||||
for key in ["temperature", "top_p", "max_tokens", "stream",
|
||||
"repetition_penalty", "profanity_check"]:
|
||||
for key in [
|
||||
"temperature",
|
||||
"top_p",
|
||||
"max_tokens",
|
||||
"stream",
|
||||
"repetition_penalty",
|
||||
"profanity_check",
|
||||
]:
|
||||
if key in optional_params:
|
||||
request_data[key] = optional_params[key]
|
||||
|
||||
|
|
@ -314,7 +336,7 @@ class GigaChatConfig(BaseConfig):
|
|||
elif role == "tool":
|
||||
message["role"] = "function"
|
||||
content = message.get("content", "")
|
||||
if not isinstance(content, str):
|
||||
if not isinstance(content, str) or not is_valid_json(content):
|
||||
message["content"] = json.dumps(content, ensure_ascii=False)
|
||||
|
||||
# Handle None content
|
||||
|
|
@ -441,14 +463,16 @@ class GigaChatConfig(BaseConfig):
|
|||
# Convert to tool_calls format
|
||||
if isinstance(args, dict):
|
||||
args = json.dumps(args, ensure_ascii=False)
|
||||
message_data["tool_calls"] = [{
|
||||
"id": f"call_{uuid.uuid4().hex[:24]}",
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": func_call.get("name", ""),
|
||||
"arguments": args,
|
||||
message_data["tool_calls"] = [
|
||||
{
|
||||
"id": f"call_{uuid.uuid4().hex[:24]}",
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": func_call.get("name", ""),
|
||||
"arguments": args,
|
||||
},
|
||||
}
|
||||
}]
|
||||
]
|
||||
message_data.pop("function_call", None)
|
||||
finish_reason = "tool_calls"
|
||||
|
||||
|
|
|
|||
|
|
@ -23,7 +23,7 @@ from ...openai.chat.gpt_transformation import OpenAIGPTConfig
|
|||
class HostedVLLMChatConfig(OpenAIGPTConfig):
|
||||
def get_supported_openai_params(self, model: str) -> List[str]:
|
||||
params = super().get_supported_openai_params(model)
|
||||
params.append("reasoning_effort")
|
||||
params.extend(["reasoning_effort", "thinking"])
|
||||
return params
|
||||
|
||||
def map_openai_params(
|
||||
|
|
@ -41,6 +41,27 @@ class HostedVLLMChatConfig(OpenAIGPTConfig):
|
|||
_tools = _remove_strict_from_schema(_tools)
|
||||
if _tools is not None:
|
||||
non_default_params["tools"] = _tools
|
||||
|
||||
# Handle thinking parameter - convert Anthropic-style to OpenAI-style reasoning_effort
|
||||
# vLLM is OpenAI-compatible, so it understands reasoning_effort, not thinking
|
||||
# Reference: https://github.com/BerriAI/litellm/issues/19761
|
||||
thinking = non_default_params.pop("thinking", None)
|
||||
if thinking is not None and isinstance(thinking, dict):
|
||||
if thinking.get("type") == "enabled":
|
||||
# Only convert if reasoning_effort not already set
|
||||
if "reasoning_effort" not in non_default_params:
|
||||
budget_tokens = thinking.get("budget_tokens", 0)
|
||||
# Map budget_tokens to reasoning_effort level
|
||||
# Same logic as Anthropic adapter (translate_anthropic_thinking_to_reasoning_effort)
|
||||
if budget_tokens >= 10000:
|
||||
non_default_params["reasoning_effort"] = "high"
|
||||
elif budget_tokens >= 5000:
|
||||
non_default_params["reasoning_effort"] = "medium"
|
||||
elif budget_tokens >= 2000:
|
||||
non_default_params["reasoning_effort"] = "low"
|
||||
else:
|
||||
non_default_params["reasoning_effort"] = "minimal"
|
||||
|
||||
return super().map_openai_params(
|
||||
non_default_params, optional_params, model, drop_params
|
||||
)
|
||||
|
|
|
|||
|
|
@ -1,11 +1,12 @@
|
|||
"""
|
||||
MiniMax OpenAI transformation config - extends OpenAI chat config for MiniMax's OpenAI-compatible API
|
||||
"""
|
||||
from typing import Optional
|
||||
from typing import List, Optional, Tuple
|
||||
|
||||
import litellm
|
||||
from litellm.llms.openai.chat.gpt_transformation import OpenAIGPTConfig
|
||||
from litellm.secret_managers.main import get_secret_str
|
||||
from litellm.types.llms.openai import AllMessageValues, ChatCompletionToolParam
|
||||
|
||||
|
||||
class MinimaxChatConfig(OpenAIGPTConfig):
|
||||
|
|
@ -73,11 +74,33 @@ class MinimaxChatConfig(OpenAIGPTConfig):
|
|||
else:
|
||||
return f"{base_url}/v1/chat/completions"
|
||||
|
||||
def remove_cache_control_flag_from_messages_and_tools(
|
||||
self,
|
||||
model: str,
|
||||
messages: List[AllMessageValues],
|
||||
tools: Optional[List[ChatCompletionToolParam]] = None,
|
||||
) -> Tuple[List[AllMessageValues], Optional[List[ChatCompletionToolParam]]]:
|
||||
"""
|
||||
Override to preserve cache_control for MiniMax.
|
||||
MiniMax supports cache_control - don't strip it.
|
||||
"""
|
||||
# MiniMax supports cache_control, so return messages and tools unchanged
|
||||
return messages, tools
|
||||
|
||||
def get_supported_openai_params(self, model: str) -> list:
|
||||
"""
|
||||
Get supported OpenAI parameters for MiniMax.
|
||||
Adds reasoning_split to the list of supported params.
|
||||
Adds reasoning_split and thinking to the list of supported params.
|
||||
"""
|
||||
base_params = super().get_supported_openai_params(model=model)
|
||||
return base_params + ["reasoning_split"]
|
||||
additional_params = ["reasoning_split"]
|
||||
|
||||
# Add thinking parameter if model supports reasoning
|
||||
try:
|
||||
if litellm.supports_reasoning(model=model, custom_llm_provider="minimax"):
|
||||
additional_params.append("thinking")
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
return base_params + additional_params
|
||||
|
||||
|
|
|
|||
|
|
@ -32,6 +32,7 @@ from litellm.types.llms.oci import (
|
|||
OCICompletionResponse,
|
||||
OCIContentPartUnion,
|
||||
OCIImageContentPart,
|
||||
OCIImageUrl,
|
||||
OCIMessage,
|
||||
OCIRoles,
|
||||
OCIServingMode,
|
||||
|
|
@ -1129,7 +1130,7 @@ def adapt_messages_to_generic_oci_standard_content_message(
|
|||
image_url = image_url.get("url")
|
||||
if not isinstance(image_url, str):
|
||||
raise Exception("Prop `image_url` must be a string or an object with a `url` property")
|
||||
new_content.append(OCIImageContentPart(imageUrl=image_url))
|
||||
new_content.append(OCIImageContentPart(imageUrl=OCIImageUrl(url=image_url)))
|
||||
|
||||
return OCIMessage(
|
||||
role=open_ai_to_generic_oci_role_map[role],
|
||||
|
|
|
|||
|
|
@ -26,6 +26,9 @@ class CacheControlSupportedModels(str, Enum):
|
|||
"""Models that support cache_control in content blocks."""
|
||||
CLAUDE = "claude"
|
||||
GEMINI = "gemini"
|
||||
MINIMAX = "minimax"
|
||||
GLM = "glm"
|
||||
ZAI = "z-ai"
|
||||
|
||||
|
||||
class OpenrouterConfig(OpenAIGPTConfig):
|
||||
|
|
@ -39,6 +42,7 @@ class OpenrouterConfig(OpenAIGPTConfig):
|
|||
model=model, custom_llm_provider="openrouter"
|
||||
) or litellm.supports_reasoning(model=model):
|
||||
supported_params.append("reasoning_effort")
|
||||
supported_params.append("thinking")
|
||||
except Exception:
|
||||
pass
|
||||
return list(dict.fromkeys(supported_params))
|
||||
|
|
|
|||
|
|
@ -849,7 +849,7 @@ def get_vertex_model_id_from_url(url: str) -> Optional[str]:
|
|||
|
||||
`https://${LOCATION}-aiplatform.googleapis.com/v1/projects/${PROJECT_ID}/locations/${LOCATION}/publishers/google/models/${MODEL_ID}:streamGenerateContent`
|
||||
"""
|
||||
match = re.search(r"/models/([^/:]+)", url)
|
||||
match = re.search(r"/models/([^:]+)", url)
|
||||
return match.group(1) if match else None
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -1,10 +1,11 @@
|
|||
from typing import TYPE_CHECKING, Any, Dict, List, Optional
|
||||
from typing import TYPE_CHECKING, Any, Dict, List, Optional, Union
|
||||
|
||||
import litellm
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.llms.openai.responses.transformation import OpenAIResponsesAPIConfig
|
||||
from litellm.secret_managers.main import get_secret_str
|
||||
from litellm.types.llms.openai import ResponsesAPIOptionalRequestParams
|
||||
from litellm.types.llms.xai import XAIWebSearchTool, XAIXSearchTool
|
||||
from litellm.types.router import GenericLiteLLMParams
|
||||
from litellm.types.utils import LlmProviders
|
||||
|
||||
|
|
@ -49,6 +50,85 @@ class XAIResponsesAPIConfig(OpenAIResponsesAPIConfig):
|
|||
|
||||
return supported_params
|
||||
|
||||
def _transform_web_search_tool(self, tool: Dict[str, Any]) -> Union[XAIWebSearchTool, Dict[str, Any]]:
|
||||
"""
|
||||
Transform web_search tool to XAI format.
|
||||
|
||||
XAI supports web_search with specific filters:
|
||||
- allowed_domains (max 5)
|
||||
- excluded_domains (max 5)
|
||||
- enable_image_understanding
|
||||
|
||||
XAI does NOT support search_context_size (OpenAI-specific).
|
||||
"""
|
||||
xai_tool: Dict[str, Any] = {"type": "web_search"}
|
||||
|
||||
# Remove search_context_size if present (not supported by XAI)
|
||||
if "search_context_size" in tool:
|
||||
verbose_logger.info(
|
||||
"XAI does not support 'search_context_size' parameter. Removing it from web_search tool."
|
||||
)
|
||||
|
||||
# Handle filters (XAI-specific structure)
|
||||
filters = {}
|
||||
if "allowed_domains" in tool:
|
||||
allowed_domains = tool["allowed_domains"]
|
||||
filters["allowed_domains"] = allowed_domains
|
||||
|
||||
if "excluded_domains" in tool:
|
||||
excluded_domains = tool["excluded_domains"]
|
||||
filters["excluded_domains"] = excluded_domains
|
||||
|
||||
# Add filters if any were specified
|
||||
if filters:
|
||||
xai_tool["filters"] = filters
|
||||
|
||||
# Handle enable_image_understanding (top-level in XAI format)
|
||||
if "enable_image_understanding" in tool:
|
||||
xai_tool["enable_image_understanding"] = tool["enable_image_understanding"]
|
||||
|
||||
return xai_tool
|
||||
|
||||
def _transform_x_search_tool(self, tool: Dict[str, Any]) -> Union[XAIXSearchTool, Dict[str, Any]]:
|
||||
"""
|
||||
Transform x_search tool to XAI format.
|
||||
|
||||
XAI supports x_search with specific parameters:
|
||||
- allowed_x_handles (max 10)
|
||||
- excluded_x_handles (max 10)
|
||||
- from_date (ISO8601: YYYY-MM-DD)
|
||||
- to_date (ISO8601: YYYY-MM-DD)
|
||||
- enable_image_understanding
|
||||
- enable_video_understanding
|
||||
"""
|
||||
xai_tool: Dict[str, Any] = {"type": "x_search"}
|
||||
|
||||
# Handle allowed_x_handles
|
||||
if "allowed_x_handles" in tool:
|
||||
allowed_handles = tool["allowed_x_handles"]
|
||||
xai_tool["allowed_x_handles"] = allowed_handles
|
||||
|
||||
# Handle excluded_x_handles
|
||||
if "excluded_x_handles" in tool:
|
||||
excluded_handles = tool["excluded_x_handles"]
|
||||
xai_tool["excluded_x_handles"] = excluded_handles
|
||||
|
||||
# Handle date range
|
||||
if "from_date" in tool:
|
||||
xai_tool["from_date"] = tool["from_date"]
|
||||
|
||||
if "to_date" in tool:
|
||||
xai_tool["to_date"] = tool["to_date"]
|
||||
|
||||
# Handle media understanding flags
|
||||
if "enable_image_understanding" in tool:
|
||||
xai_tool["enable_image_understanding"] = tool["enable_image_understanding"]
|
||||
|
||||
if "enable_video_understanding" in tool:
|
||||
xai_tool["enable_video_understanding"] = tool["enable_video_understanding"]
|
||||
|
||||
return xai_tool
|
||||
|
||||
def map_openai_params(
|
||||
self,
|
||||
response_api_optional_params: ResponsesAPIOptionalRequestParams,
|
||||
|
|
@ -61,7 +141,9 @@ class XAIResponsesAPIConfig(OpenAIResponsesAPIConfig):
|
|||
Handles XAI-specific transformations:
|
||||
1. Drops 'instructions' parameter (not supported)
|
||||
2. Transforms code_interpreter tools to remove 'container' field
|
||||
3. Sets store=false when images are detected (recommended by XAI)
|
||||
3. Transforms web_search tools to XAI format (removes search_context_size, adds filters)
|
||||
4. Transforms x_search tools to XAI format
|
||||
5. Sets store=false when images are detected (recommended by XAI)
|
||||
"""
|
||||
params = dict(response_api_optional_params)
|
||||
|
||||
|
|
@ -72,7 +154,7 @@ class XAIResponsesAPIConfig(OpenAIResponsesAPIConfig):
|
|||
)
|
||||
params.pop("instructions")
|
||||
|
||||
# Transform code_interpreter tools - remove container field
|
||||
# Transform tools
|
||||
if "tools" in params and params["tools"]:
|
||||
tools_list = params["tools"]
|
||||
# Ensure tools is a list for iteration
|
||||
|
|
@ -81,15 +163,36 @@ class XAIResponsesAPIConfig(OpenAIResponsesAPIConfig):
|
|||
|
||||
transformed_tools: List[Any] = []
|
||||
for tool in tools_list:
|
||||
if isinstance(tool, dict) and tool.get("type") == "code_interpreter":
|
||||
# XAI supports code_interpreter but doesn't use the container field
|
||||
# Keep only the type field
|
||||
verbose_logger.debug(
|
||||
"XAI: Transforming code_interpreter tool, removing container field"
|
||||
)
|
||||
transformed_tools.append({"type": "code_interpreter"})
|
||||
if isinstance(tool, dict):
|
||||
tool_type = tool.get("type")
|
||||
|
||||
if tool_type == "code_interpreter":
|
||||
# XAI supports code_interpreter but doesn't use the container field
|
||||
verbose_logger.debug(
|
||||
"XAI: Transforming code_interpreter tool, removing container field"
|
||||
)
|
||||
transformed_tools.append({"type": "code_interpreter"})
|
||||
|
||||
elif tool_type == "web_search":
|
||||
# Transform web_search to XAI format
|
||||
verbose_logger.debug(
|
||||
"XAI: Transforming web_search tool to XAI format"
|
||||
)
|
||||
transformed_tools.append(self._transform_web_search_tool(tool))
|
||||
|
||||
elif tool_type == "x_search":
|
||||
# Transform x_search to XAI format
|
||||
verbose_logger.debug(
|
||||
"XAI: Transforming x_search tool to XAI format"
|
||||
)
|
||||
transformed_tools.append(self._transform_x_search_tool(tool))
|
||||
|
||||
else:
|
||||
# Keep other tools as-is
|
||||
transformed_tools.append(tool)
|
||||
else:
|
||||
transformed_tools.append(tool)
|
||||
|
||||
params["tools"] = transformed_tools
|
||||
|
||||
return params
|
||||
|
|
|
|||
|
|
@ -1,6 +1,7 @@
|
|||
from typing import Optional, Tuple
|
||||
from typing import List, Optional, Tuple
|
||||
|
||||
from litellm.secret_managers.main import get_secret_str
|
||||
from litellm.types.llms.openai import AllMessageValues, ChatCompletionToolParam
|
||||
|
||||
from ...openai.chat.gpt_transformation import OpenAIGPTConfig
|
||||
|
||||
|
|
@ -19,6 +20,19 @@ class ZAIChatConfig(OpenAIGPTConfig):
|
|||
dynamic_api_key = api_key or get_secret_str("ZAI_API_KEY")
|
||||
return api_base, dynamic_api_key
|
||||
|
||||
def remove_cache_control_flag_from_messages_and_tools(
|
||||
self,
|
||||
model: str,
|
||||
messages: List[AllMessageValues],
|
||||
tools: Optional[List[ChatCompletionToolParam]] = None,
|
||||
) -> Tuple[List[AllMessageValues], Optional[List[ChatCompletionToolParam]]]:
|
||||
"""
|
||||
Override to preserve cache_control for GLM/ZAI.
|
||||
GLM supports cache_control - don't strip it.
|
||||
"""
|
||||
# GLM/ZAI supports cache_control, so return messages and tools unchanged
|
||||
return messages, tools
|
||||
|
||||
def get_supported_openai_params(self, model: str) -> list:
|
||||
base_params = [
|
||||
"max_tokens",
|
||||
|
|
|
|||
|
|
@ -599,15 +599,8 @@ async def acompletion( # noqa: PLR0915
|
|||
# Add the context to the function
|
||||
ctx = contextvars.copy_context()
|
||||
func_with_context = partial(ctx.run, func)
|
||||
|
||||
if timeout is not None and isinstance(timeout, (int, float)):
|
||||
timeout_value = float(timeout)
|
||||
init_response = await asyncio.wait_for(
|
||||
loop.run_in_executor(None, func_with_context), timeout=timeout_value
|
||||
)
|
||||
else:
|
||||
init_response = await loop.run_in_executor(None, func_with_context)
|
||||
|
||||
|
||||
init_response = await loop.run_in_executor(None, func_with_context)
|
||||
if isinstance(init_response, dict) or isinstance(
|
||||
init_response, ModelResponse
|
||||
): ## CACHING SCENARIO
|
||||
|
|
@ -615,11 +608,7 @@ async def acompletion( # noqa: PLR0915
|
|||
response = ModelResponse(**init_response)
|
||||
response = init_response
|
||||
elif asyncio.iscoroutine(init_response):
|
||||
if timeout is not None and isinstance(timeout, (int, float)):
|
||||
timeout_value = float(timeout)
|
||||
response = await asyncio.wait_for(init_response, timeout=timeout_value)
|
||||
else:
|
||||
response = await init_response
|
||||
response = await init_response
|
||||
else:
|
||||
response = init_response # type: ignore
|
||||
|
||||
|
|
@ -636,15 +625,6 @@ async def acompletion( # noqa: PLR0915
|
|||
loop=loop
|
||||
) # sets the logging event loop if the user does sync streaming (e.g. on proxy for sagemaker calls)
|
||||
return response
|
||||
except asyncio.TimeoutError:
|
||||
custom_llm_provider = custom_llm_provider or "openai"
|
||||
from litellm.exceptions import Timeout
|
||||
|
||||
raise Timeout(
|
||||
message=f"Request timed out after {timeout} seconds",
|
||||
model=model,
|
||||
llm_provider=custom_llm_provider,
|
||||
)
|
||||
except Exception as e:
|
||||
custom_llm_provider = custom_llm_provider or "openai"
|
||||
raise exception_type(
|
||||
|
|
|
|||
|
|
@ -3653,10 +3653,9 @@
|
|||
"max_input_tokens": 128000,
|
||||
"max_output_tokens": 16384,
|
||||
"max_tokens": 16384,
|
||||
"mode": "chat",
|
||||
"mode": "responses",
|
||||
"output_cost_per_token": 1.4e-05,
|
||||
"supported_endpoints": [
|
||||
"/v1/chat/completions",
|
||||
"/v1/responses"
|
||||
],
|
||||
"supported_modalities": [
|
||||
|
|
@ -13523,6 +13522,42 @@
|
|||
"supports_web_search": true
|
||||
},
|
||||
"gemini-robotics-er-1.5-preview": {
|
||||
"cache_read_input_token_cost": 0,
|
||||
"input_cost_per_token": 3e-07,
|
||||
"input_cost_per_audio_token": 1e-06,
|
||||
"litellm_provider": "vertex_ai-language-models",
|
||||
"max_input_tokens": 1048576,
|
||||
"max_output_tokens": 65535,
|
||||
"max_tokens": 65535,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 2.5e-06,
|
||||
"output_cost_per_reasoning_token": 2.5e-06,
|
||||
"source": "https://ai.google.dev/gemini-api/docs/models#gemini-robotics-er-1-5-preview",
|
||||
"supported_endpoints": [
|
||||
"/v1/chat/completions",
|
||||
"/v1/completions"
|
||||
],
|
||||
"supported_modalities": [
|
||||
"text",
|
||||
"image",
|
||||
"video",
|
||||
"audio"
|
||||
],
|
||||
"supported_output_modalities": [
|
||||
"text"
|
||||
],
|
||||
"supports_audio_output": false,
|
||||
"supports_function_calling": true,
|
||||
"supports_parallel_function_calling": true,
|
||||
"supports_prompt_caching": false,
|
||||
"supports_reasoning": true,
|
||||
"supports_response_schema": true,
|
||||
"supports_system_messages": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_url_context": true,
|
||||
"supports_vision": true
|
||||
},
|
||||
"gemini/gemini-robotics-er-1.5-preview": {
|
||||
"cache_read_input_token_cost": 0,
|
||||
"input_cost_per_token": 3e-07,
|
||||
"input_cost_per_audio_token": 1e-06,
|
||||
|
|
@ -20628,6 +20663,7 @@
|
|||
"supports_function_calling": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_system_messages": true,
|
||||
"max_input_tokens": 1000000,
|
||||
"max_output_tokens": 8192
|
||||
|
|
@ -20642,6 +20678,7 @@
|
|||
"supports_function_calling": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_system_messages": true,
|
||||
"max_input_tokens": 1000000,
|
||||
"max_output_tokens": 8192
|
||||
|
|
@ -20656,6 +20693,7 @@
|
|||
"supports_function_calling": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_system_messages": true,
|
||||
"max_input_tokens": 200000,
|
||||
"max_output_tokens": 8192
|
||||
|
|
@ -23540,7 +23578,7 @@
|
|||
"mode": "chat",
|
||||
"output_cost_per_token": 1.02e-06,
|
||||
"supports_function_calling": true,
|
||||
"supports_prompt_caching": false,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
|
|
@ -23892,8 +23930,11 @@
|
|||
"max_input_tokens": 400000,
|
||||
"max_output_tokens": 128000,
|
||||
"max_tokens": 128000,
|
||||
"mode": "chat",
|
||||
"mode": "responses",
|
||||
"output_cost_per_token": 1.4e-05,
|
||||
"supported_endpoints": [
|
||||
"/v1/responses"
|
||||
],
|
||||
"supported_modalities": [
|
||||
"text",
|
||||
"image"
|
||||
|
|
@ -24232,6 +24273,7 @@
|
|||
"output_cost_per_token": 1.75e-06,
|
||||
"source": "https://openrouter.ai/z-ai/glm-4.6",
|
||||
"supports_function_calling": true,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
|
|
@ -24245,9 +24287,76 @@
|
|||
"output_cost_per_token": 1.9e-06,
|
||||
"source": "https://openrouter.ai/z-ai/glm-4.6:exacto",
|
||||
"supports_function_calling": true,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
"openrouter/xiaomi/mimo-v2-flash": {
|
||||
"input_cost_per_token": 9e-08,
|
||||
"output_cost_per_token": 2.9e-07,
|
||||
"cache_creation_input_token_cost": 0.0,
|
||||
"cache_read_input_token_cost": 0.0,
|
||||
"litellm_provider": "openrouter",
|
||||
"max_input_tokens": 262144,
|
||||
"max_output_tokens": 16384,
|
||||
"max_tokens": 16384,
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_vision": false,
|
||||
"supports_prompt_caching": false
|
||||
},
|
||||
"openrouter/z-ai/glm-4.7": {
|
||||
"input_cost_per_token": 4e-07,
|
||||
"output_cost_per_token": 1.5e-06,
|
||||
"cache_creation_input_token_cost": 0.0,
|
||||
"cache_read_input_token_cost": 0.0,
|
||||
"litellm_provider": "openrouter",
|
||||
"max_input_tokens": 202752,
|
||||
"max_output_tokens": 64000,
|
||||
"max_tokens": 64000,
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_vision": true,
|
||||
"supports_prompt_caching": false,
|
||||
"supports_assistant_prefill": true
|
||||
},
|
||||
"openrouter/z-ai/glm-4.7-flash": {
|
||||
"input_cost_per_token": 7e-08,
|
||||
"output_cost_per_token": 4e-07,
|
||||
"cache_creation_input_token_cost": 0.0,
|
||||
"cache_read_input_token_cost": 0.0,
|
||||
"litellm_provider": "openrouter",
|
||||
"max_input_tokens": 200000,
|
||||
"max_output_tokens": 32000,
|
||||
"max_tokens": 32000,
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_vision": true,
|
||||
"supports_prompt_caching": false
|
||||
},
|
||||
"openrouter/minimax/minimax-m2.1": {
|
||||
"input_cost_per_token": 2.7e-07,
|
||||
"output_cost_per_token": 1.2e-06,
|
||||
"cache_creation_input_token_cost": 0.0,
|
||||
"cache_read_input_token_cost": 0.0,
|
||||
"litellm_provider": "openrouter",
|
||||
"max_input_tokens": 204000,
|
||||
"max_output_tokens": 64000,
|
||||
"max_tokens": 64000,
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_vision": true,
|
||||
"supports_prompt_caching": false,
|
||||
"supports_computer_use": false
|
||||
},
|
||||
"ovhcloud/DeepSeek-R1-Distill-Llama-70B": {
|
||||
"input_cost_per_token": 6.7e-07,
|
||||
"litellm_provider": "ovhcloud",
|
||||
|
|
@ -30461,6 +30570,7 @@
|
|||
"supports_web_search": true
|
||||
},
|
||||
"xai/grok-3": {
|
||||
"cache_read_input_token_cost": 7.5e-07,
|
||||
"input_cost_per_token": 3e-06,
|
||||
"litellm_provider": "xai",
|
||||
"max_input_tokens": 131072,
|
||||
|
|
@ -30475,6 +30585,7 @@
|
|||
"supports_web_search": true
|
||||
},
|
||||
"xai/grok-3-beta": {
|
||||
"cache_read_input_token_cost": 7.5e-07,
|
||||
"input_cost_per_token": 3e-06,
|
||||
"litellm_provider": "xai",
|
||||
"max_input_tokens": 131072,
|
||||
|
|
@ -30489,6 +30600,7 @@
|
|||
"supports_web_search": true
|
||||
},
|
||||
"xai/grok-3-fast-beta": {
|
||||
"cache_read_input_token_cost": 1.25e-06,
|
||||
"input_cost_per_token": 5e-06,
|
||||
"litellm_provider": "xai",
|
||||
"max_input_tokens": 131072,
|
||||
|
|
@ -30503,6 +30615,7 @@
|
|||
"supports_web_search": true
|
||||
},
|
||||
"xai/grok-3-fast-latest": {
|
||||
"cache_read_input_token_cost": 1.25e-06,
|
||||
"input_cost_per_token": 5e-06,
|
||||
"litellm_provider": "xai",
|
||||
"max_input_tokens": 131072,
|
||||
|
|
@ -30517,6 +30630,7 @@
|
|||
"supports_web_search": true
|
||||
},
|
||||
"xai/grok-3-latest": {
|
||||
"cache_read_input_token_cost": 7.5e-07,
|
||||
"input_cost_per_token": 3e-06,
|
||||
"litellm_provider": "xai",
|
||||
"max_input_tokens": 131072,
|
||||
|
|
@ -30531,6 +30645,7 @@
|
|||
"supports_web_search": true
|
||||
},
|
||||
"xai/grok-3-mini": {
|
||||
"cache_read_input_token_cost": 7.5e-08,
|
||||
"input_cost_per_token": 3e-07,
|
||||
"litellm_provider": "xai",
|
||||
"max_input_tokens": 131072,
|
||||
|
|
@ -30546,6 +30661,7 @@
|
|||
"supports_web_search": true
|
||||
},
|
||||
"xai/grok-3-mini-beta": {
|
||||
"cache_read_input_token_cost": 7.5e-08,
|
||||
"input_cost_per_token": 3e-07,
|
||||
"litellm_provider": "xai",
|
||||
"max_input_tokens": 131072,
|
||||
|
|
@ -30561,6 +30677,7 @@
|
|||
"supports_web_search": true
|
||||
},
|
||||
"xai/grok-3-mini-fast": {
|
||||
"cache_read_input_token_cost": 1.5e-07,
|
||||
"input_cost_per_token": 6e-07,
|
||||
"litellm_provider": "xai",
|
||||
"max_input_tokens": 131072,
|
||||
|
|
@ -30576,6 +30693,7 @@
|
|||
"supports_web_search": true
|
||||
},
|
||||
"xai/grok-3-mini-fast-beta": {
|
||||
"cache_read_input_token_cost": 1.5e-07,
|
||||
"input_cost_per_token": 6e-07,
|
||||
"litellm_provider": "xai",
|
||||
"max_input_tokens": 131072,
|
||||
|
|
@ -30591,6 +30709,7 @@
|
|||
"supports_web_search": true
|
||||
},
|
||||
"xai/grok-3-mini-fast-latest": {
|
||||
"cache_read_input_token_cost": 1.5e-07,
|
||||
"input_cost_per_token": 6e-07,
|
||||
"litellm_provider": "xai",
|
||||
"max_input_tokens": 131072,
|
||||
|
|
@ -30606,6 +30725,7 @@
|
|||
"supports_web_search": true
|
||||
},
|
||||
"xai/grok-3-mini-latest": {
|
||||
"cache_read_input_token_cost": 7.5e-08,
|
||||
"input_cost_per_token": 3e-07,
|
||||
"litellm_provider": "xai",
|
||||
"max_input_tokens": 131072,
|
||||
|
|
@ -30872,11 +30992,14 @@
|
|||
"max_output_tokens": 128000,
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true,
|
||||
"source": "https://docs.z.ai/guides/overview/pricing"
|
||||
},
|
||||
"zai/glm-4.6": {
|
||||
"cache_creation_input_token_cost": 0,
|
||||
"cache_read_input_token_cost": 1.1e-07,
|
||||
"input_cost_per_token": 6e-07,
|
||||
"output_cost_per_token": 2.2e-06,
|
||||
"litellm_provider": "zai",
|
||||
|
|
@ -30884,6 +31007,8 @@
|
|||
"max_output_tokens": 128000,
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true,
|
||||
"source": "https://docs.z.ai/guides/overview/pricing"
|
||||
},
|
||||
|
|
@ -34531,4 +34656,4 @@
|
|||
"output_cost_per_token": 0,
|
||||
"supports_reasoning": true
|
||||
}
|
||||
}
|
||||
}
|
||||
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue