fix langfuse otel missing traces
 Harshit Jain
|
|
@ -112,6 +112,24 @@ jobs:
|
|||
python -m mypy .
|
||||
cd ..
|
||||
no_output_timeout: 10m
|
||||
|
||||
semgrep:
|
||||
docker:
|
||||
- image: cimg/python:3.12
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
- run:
|
||||
name: Install Semgrep
|
||||
command: pip install semgrep
|
||||
- run:
|
||||
name: Run Semgrep (custom rules only)
|
||||
command: semgrep scan --config .semgrep/rules . --error
|
||||
|
||||
local_testing_part1:
|
||||
docker:
|
||||
- image: cimg/python:3.12
|
||||
|
|
@ -1255,7 +1273,15 @@ jobs:
|
|||
ls
|
||||
# Add --timeout to kill hanging tests after 120s (2 min)
|
||||
# Add --durations=20 to show 20 slowest tests for debugging
|
||||
python -m pytest -vv tests/llm_translation --cov=litellm --cov-report=xml -v --junitxml=test-results/junit.xml --durations=20 -n 4 --timeout=120 --timeout_method=thread
|
||||
# Subdirectories with dedicated jobs (maintain this list as new jobs are added)
|
||||
IGNORE_DIRS=(
|
||||
"tests/llm_translation/realtime"
|
||||
)
|
||||
IGNORE_ARGS=""
|
||||
for dir in "${IGNORE_DIRS[@]}"; do
|
||||
IGNORE_ARGS="$IGNORE_ARGS --ignore=$dir"
|
||||
done
|
||||
python -m pytest -vv tests/llm_translation $IGNORE_ARGS --cov=litellm --cov-report=xml -v --junitxml=test-results/junit.xml --durations=20 -n 4 --timeout=120 --timeout_method=thread
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
|
|
@ -1271,6 +1297,54 @@ jobs:
|
|||
paths:
|
||||
- llm_translation_coverage.xml
|
||||
- llm_translation_coverage
|
||||
realtime_translation_testing:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
- run:
|
||||
name: Install Dependencies
|
||||
command: |
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install -r requirements.txt
|
||||
pip install "pytest==7.3.1"
|
||||
pip install "pytest-retry==1.6.3"
|
||||
pip install "pytest-cov==5.0.0"
|
||||
pip install "pytest-asyncio==0.21.1"
|
||||
pip install "respx==0.22.0"
|
||||
pip install "pytest-xdist==3.6.1"
|
||||
pip install "pytest-timeout==2.2.0"
|
||||
pip install "websockets"
|
||||
# Run pytest and generate JUnit XML report
|
||||
- run:
|
||||
name: Run realtime tests
|
||||
command: |
|
||||
pwd
|
||||
ls
|
||||
# Add --timeout to kill hanging tests after 120s (2 min)
|
||||
# Add --durations=20 to show 20 slowest tests for debugging
|
||||
python -m pytest -vv tests/llm_translation/realtime --cov=litellm --cov-report=xml -v --junitxml=test-results/junit.xml --durations=20 -n 4 --timeout=120 --timeout_method=thread
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml realtime_translation_coverage.xml
|
||||
mv .coverage realtime_translation_coverage
|
||||
|
||||
# Store test results
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- realtime_translation_coverage.xml
|
||||
- realtime_translation_coverage
|
||||
mcp_testing:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
|
|
@ -1316,6 +1390,51 @@ jobs:
|
|||
paths:
|
||||
- mcp_coverage.xml
|
||||
- mcp_coverage
|
||||
agent_testing:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
- run:
|
||||
name: Install Dependencies
|
||||
command: |
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install -r requirements.txt
|
||||
pip install "pytest==7.3.1"
|
||||
pip install "pytest-retry==1.6.3"
|
||||
pip install "pytest-cov==5.0.0"
|
||||
pip install "pytest-asyncio==0.21.1"
|
||||
pip install "respx==0.22.0"
|
||||
pip install "pydantic==2.11.0"
|
||||
pip install "a2a-sdk"
|
||||
# Run pytest and generate JUnit XML report
|
||||
- run:
|
||||
name: Run tests
|
||||
command: |
|
||||
pwd
|
||||
ls
|
||||
python -m pytest -vv tests/agent_tests --ignore=tests/agent_tests/local_only_agent_tests --cov=litellm --cov-report=xml -x -s -v --junitxml=test-results/junit.xml --durations=5
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml agent_coverage.xml
|
||||
mv .coverage agent_coverage
|
||||
|
||||
# Store test results
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- agent_coverage.xml
|
||||
- agent_coverage
|
||||
guardrails_testing:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
|
|
@ -1537,7 +1656,7 @@ jobs:
|
|||
- search_coverage.xml
|
||||
- search_coverage
|
||||
# Split litellm_mapped_tests into 3 parallel jobs for 3x faster execution
|
||||
litellm_mapped_tests_proxy:
|
||||
litellm_mapped_tests_proxy_part1:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
|
|
@ -1548,23 +1667,53 @@ jobs:
|
|||
steps:
|
||||
- setup_litellm_test_deps
|
||||
- run:
|
||||
name: Run proxy tests
|
||||
name: Run proxy tests part 1 (high-volume directories)
|
||||
command: |
|
||||
prisma generate
|
||||
python -m pytest tests/test_litellm/proxy --cov=litellm --cov-report=xml --junitxml=test-results/junit-proxy.xml --durations=10 -n 16 --maxfail=5 --timeout=300 -vv --log-cli-level=WARNING
|
||||
no_output_timeout: 120m
|
||||
export PYTHONUNBUFFERED=1
|
||||
python -m pytest tests/test_litellm/proxy/guardrails tests/test_litellm/proxy/management_endpoints tests/test_litellm/proxy/_experimental tests/test_litellm/proxy/client tests/test_litellm/proxy/auth --cov=litellm --cov-report=xml --junitxml=test-results/junit-proxy-part1.xml --durations=10 -n 8 --maxfail=5 --timeout=60 -vv --log-cli-level=WARNING -r A
|
||||
no_output_timeout: 60m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml litellm_proxy_tests_coverage.xml
|
||||
mv .coverage litellm_proxy_tests_coverage
|
||||
mv coverage.xml litellm_proxy_tests_part1_coverage.xml
|
||||
mv .coverage litellm_proxy_tests_part1_coverage
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm_proxy_tests_coverage.xml
|
||||
- litellm_proxy_tests_coverage
|
||||
- litellm_proxy_tests_part1_coverage.xml
|
||||
- litellm_proxy_tests_part1_coverage
|
||||
litellm_mapped_tests_proxy_part2:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
resource_class: xlarge
|
||||
steps:
|
||||
- setup_litellm_test_deps
|
||||
- run:
|
||||
name: Run proxy tests part 2 (all other tests)
|
||||
command: |
|
||||
prisma generate
|
||||
export PYTHONUNBUFFERED=1
|
||||
python -m pytest tests/test_litellm/proxy --ignore=tests/test_litellm/proxy/guardrails --ignore=tests/test_litellm/proxy/management_endpoints --ignore=tests/test_litellm/proxy/_experimental --ignore=tests/test_litellm/proxy/client --ignore=tests/test_litellm/proxy/auth --cov=litellm --cov-report=xml --junitxml=test-results/junit-proxy-part2.xml --durations=10 -n 8 --maxfail=5 --timeout=60 -vv --log-cli-level=WARNING -r A
|
||||
no_output_timeout: 60m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml litellm_proxy_tests_part2_coverage.xml
|
||||
mv .coverage litellm_proxy_tests_part2_coverage
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm_proxy_tests_part2_coverage.xml
|
||||
- litellm_proxy_tests_part2_coverage
|
||||
litellm_mapped_tests_llms:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
|
|
@ -1605,7 +1754,7 @@ jobs:
|
|||
- run:
|
||||
name: Run core tests
|
||||
command: |
|
||||
python -m pytest tests/test_litellm --ignore=tests/test_litellm/proxy --ignore=tests/test_litellm/llms --ignore=tests/test_litellm/integrations --ignore=tests/test_litellm/litellm_core_utils --cov=litellm --cov-report=xml --junitxml=test-results/junit-core.xml --durations=10 -n 16 --maxfail=5 --timeout=300 -vv --log-cli-level=WARNING
|
||||
python -m pytest tests/test_litellm --ignore=tests/test_litellm/proxy --ignore=tests/test_litellm/llms --ignore=tests/test_litellm/integrations --ignore=tests/test_litellm/litellm_core_utils --ignore=tests/test_litellm/experimental_mcp_client --cov=litellm --cov-report=xml --junitxml=test-results/junit-core.xml --durations=10 -n 16 --maxfail=5 --timeout=300 -vv --log-cli-level=WARNING
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
|
|
@ -1646,6 +1795,33 @@ jobs:
|
|||
paths:
|
||||
- litellm_core_utils_tests_coverage.xml
|
||||
- litellm_core_utils_tests_coverage
|
||||
litellm_mapped_tests_mcps:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
resource_class: xlarge
|
||||
steps:
|
||||
- setup_litellm_test_deps
|
||||
- run:
|
||||
name: Run MCP client tests
|
||||
command: |
|
||||
python -m pytest tests/test_litellm/experimental_mcp_client --cov=litellm --cov-report=xml --junitxml=test-results/junit-mcps.xml --durations=10 -n 4 --maxfail=5 --timeout=300 -vv --log-cli-level=WARNING
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml litellm_mcps_tests_coverage.xml
|
||||
mv .coverage litellm_mcps_tests_coverage
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm_mcps_tests_coverage.xml
|
||||
- litellm_mcps_tests_coverage
|
||||
litellm_mapped_tests_integrations:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
|
|
@ -2176,6 +2352,7 @@ jobs:
|
|||
- run: python ./tests/code_coverage_tests/router_code_coverage.py
|
||||
- run: python ./tests/code_coverage_tests/test_chat_completion_imports.py
|
||||
- run: python ./tests/code_coverage_tests/info_log_check.py
|
||||
- run: python ./tests/code_coverage_tests/check_guardrail_apply_decorator.py
|
||||
- run: python ./tests/code_coverage_tests/test_ban_set_verbose.py
|
||||
- run: python ./tests/code_coverage_tests/code_qa_check_tests.py
|
||||
- run: python ./tests/code_coverage_tests/check_get_model_cost_key_performance.py
|
||||
|
|
@ -3477,9 +3654,11 @@ jobs:
|
|||
-p 4000:4000 \
|
||||
-e DATABASE_URL=postgresql://postgres:postgres@host.docker.internal:5432/circle_test \
|
||||
-e LITELLM_MASTER_KEY="sk-1234" \
|
||||
-e ANTHROPIC_API_KEY=$ANTHROPIC_API_KEY \
|
||||
-e AWS_ACCESS_KEY_ID=$AWS_ACCESS_KEY_ID \
|
||||
-e AWS_SECRET_ACCESS_KEY=$AWS_SECRET_ACCESS_KEY \
|
||||
-e AWS_REGION_NAME="us-east-1" \
|
||||
-e LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS="True" \
|
||||
--add-host host.docker.internal:host-gateway \
|
||||
--name my-app \
|
||||
-v $(pwd)/tests/proxy_e2e_anthropic_messages_tests/test_config.yaml:/app/config.yaml \
|
||||
|
|
@ -3532,7 +3711,7 @@ jobs:
|
|||
python -m venv venv
|
||||
. venv/bin/activate
|
||||
pip install coverage
|
||||
coverage combine llm_translation_coverage llm_responses_api_coverage ocr_coverage search_coverage mcp_coverage logging_coverage audio_coverage litellm_router_coverage litellm_router_unit_coverage local_testing_part1_coverage local_testing_part2_coverage litellm_assistants_api_coverage auth_ui_unit_tests_coverage langfuse_coverage caching_coverage litellm_proxy_unit_tests_part1_coverage litellm_proxy_unit_tests_part2_coverage image_gen_coverage pass_through_unit_tests_coverage batches_coverage litellm_security_tests_coverage guardrails_coverage litellm_mapped_tests_coverage
|
||||
coverage combine llm_translation_coverage realtime_translation_coverage llm_responses_api_coverage ocr_coverage search_coverage mcp_coverage litellm_mcps_tests_coverage logging_coverage audio_coverage litellm_router_coverage litellm_router_unit_coverage local_testing_part1_coverage local_testing_part2_coverage litellm_assistants_api_coverage auth_ui_unit_tests_coverage langfuse_coverage caching_coverage litellm_proxy_unit_tests_part1_coverage litellm_proxy_unit_tests_part2_coverage image_gen_coverage pass_through_unit_tests_coverage batches_coverage litellm_security_tests_coverage guardrails_coverage litellm_mapped_tests_coverage
|
||||
coverage xml
|
||||
- codecov/upload:
|
||||
file: ./coverage.xml
|
||||
|
|
@ -3700,7 +3879,6 @@ jobs:
|
|||
- run:
|
||||
name: Get new version
|
||||
command: |
|
||||
cd litellm-proxy-extras
|
||||
NEW_VERSION=$(python -c "import toml; print(toml.load('pyproject.toml')['tool']['poetry']['version'])")
|
||||
echo "export NEW_VERSION=$NEW_VERSION" >> $BASH_ENV
|
||||
|
||||
|
|
@ -3725,7 +3903,6 @@ jobs:
|
|||
- run:
|
||||
name: Publish to PyPI
|
||||
command: |
|
||||
cd litellm-proxy-extras
|
||||
echo -e "[pypi]\nusername = $PYPI_PUBLISH_USERNAME\npassword = $PYPI_PUBLISH_PASSWORD" > ~/.pypirc
|
||||
python -m pip install --upgrade pip build twine setuptools wheel
|
||||
rm -rf build dist
|
||||
|
|
@ -3832,6 +4009,9 @@ jobs:
|
|||
image: ubuntu-2204:2023.10.1
|
||||
resource_class: xlarge
|
||||
working_directory: ~/project
|
||||
parameters:
|
||||
browser:
|
||||
type: string
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
|
|
@ -3861,7 +4041,7 @@ jobs:
|
|||
echo "Expires at: $EXPIRES_AT"
|
||||
neon branches create \
|
||||
--project-id $NEON_PROJECT_ID \
|
||||
--name preview/commit-${CIRCLE_SHA1:0:7} \
|
||||
--name preview/commit-${CIRCLE_SHA1:0:7}-<< parameters.browser >> \
|
||||
--expires-at $EXPIRES_AT \
|
||||
--parent br-fancy-paper-ad1olsb3 \
|
||||
--api-key $NEON_API_KEY || true
|
||||
|
|
@ -3871,7 +4051,7 @@ jobs:
|
|||
E2E_UI_TEST_DATABASE_URL=$(neon connection-string \
|
||||
--project-id $NEON_PROJECT_ID \
|
||||
--api-key $NEON_API_KEY \
|
||||
--branch preview/commit-${CIRCLE_SHA1:0:7} \
|
||||
--branch preview/commit-${CIRCLE_SHA1:0:7}-<< parameters.browser >> \
|
||||
--database-name yuneng-trial-db \
|
||||
--role neondb_owner)
|
||||
echo $E2E_UI_TEST_DATABASE_URL
|
||||
|
|
@ -3883,7 +4063,7 @@ jobs:
|
|||
-e UI_USERNAME="admin" \
|
||||
-e UI_PASSWORD="gm" \
|
||||
-e LITELLM_LICENSE=$LITELLM_LICENSE \
|
||||
--name litellm-docker-database \
|
||||
--name litellm-docker-database-<< parameters.browser >> \
|
||||
-v $(pwd)/litellm/proxy/example_config_yaml/simple_config.yaml:/app/config.yaml \
|
||||
litellm-docker-database:ci \
|
||||
--config /app/config.yaml \
|
||||
|
|
@ -3899,7 +4079,7 @@ jobs:
|
|||
sudo rm dockerize-linux-amd64-v0.6.1.tar.gz
|
||||
- run:
|
||||
name: Start outputting logs
|
||||
command: docker logs -f litellm-docker-database
|
||||
command: docker logs -f litellm-docker-database-<< parameters.browser >>
|
||||
background: true
|
||||
- run:
|
||||
name: Wait for app to be ready
|
||||
|
|
@ -3908,6 +4088,7 @@ jobs:
|
|||
name: Run Playwright Tests
|
||||
command: |
|
||||
npx playwright test \
|
||||
--project << parameters.browser >> \
|
||||
--config ui/litellm-dashboard/e2e_tests/playwright.config.ts \
|
||||
--reporter=html \
|
||||
--output=test-results
|
||||
|
|
@ -4014,6 +4195,12 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- semgrep:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- local_testing_part1:
|
||||
filters:
|
||||
branches:
|
||||
|
|
@ -4113,6 +4300,20 @@ workflows:
|
|||
- main
|
||||
- /litellm_.*/
|
||||
- e2e_ui_testing:
|
||||
name: e2e_ui_testing_chromium
|
||||
browser: chromium
|
||||
context: e2e_ui_tests
|
||||
requires:
|
||||
- ui_build
|
||||
- build_docker_database_image
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- e2e_ui_testing:
|
||||
name: e2e_ui_testing_firefox
|
||||
browser: firefox
|
||||
context: e2e_ui_tests
|
||||
requires:
|
||||
- ui_build
|
||||
|
|
@ -4196,12 +4397,24 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- realtime_translation_testing:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- mcp_testing:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- agent_testing:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- guardrails_testing:
|
||||
filters:
|
||||
branches:
|
||||
|
|
@ -4238,7 +4451,13 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_mapped_tests_proxy:
|
||||
- litellm_mapped_tests_proxy_part1:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_mapped_tests_proxy_part2:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
|
|
@ -4256,6 +4475,12 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_mapped_tests_mcps:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_mapped_tests_integrations:
|
||||
filters:
|
||||
branches:
|
||||
|
|
@ -4307,15 +4532,19 @@ workflows:
|
|||
- upload-coverage:
|
||||
requires:
|
||||
- llm_translation_testing
|
||||
- realtime_translation_testing
|
||||
- mcp_testing
|
||||
- agent_testing
|
||||
- google_generate_content_endpoint_testing
|
||||
- guardrails_testing
|
||||
- llm_responses_api_testing
|
||||
- ocr_testing
|
||||
- search_testing
|
||||
- litellm_mapped_tests_proxy
|
||||
- litellm_mapped_tests_proxy_part1
|
||||
- litellm_mapped_tests_proxy_part2
|
||||
- litellm_mapped_tests_llms
|
||||
- litellm_mapped_tests_core
|
||||
- litellm_mapped_tests_mcps
|
||||
- litellm_mapped_tests_integrations
|
||||
- litellm_mapped_tests_litellm_core_utils
|
||||
- litellm_mapped_enterprise_tests
|
||||
|
|
@ -4378,20 +4607,25 @@ workflows:
|
|||
- publish_to_pypi:
|
||||
requires:
|
||||
- mypy_linting
|
||||
- semgrep
|
||||
- local_testing_part1
|
||||
- local_testing_part2
|
||||
- build_and_test
|
||||
- e2e_openai_endpoints
|
||||
- test_bad_database_url
|
||||
- llm_translation_testing
|
||||
- realtime_translation_testing
|
||||
- mcp_testing
|
||||
- agent_testing
|
||||
- google_generate_content_endpoint_testing
|
||||
- llm_responses_api_testing
|
||||
- ocr_testing
|
||||
- search_testing
|
||||
- litellm_mapped_tests_proxy
|
||||
- litellm_mapped_tests_proxy_part1
|
||||
- litellm_mapped_tests_proxy_part2
|
||||
- litellm_mapped_tests_llms
|
||||
- litellm_mapped_tests_core
|
||||
- litellm_mapped_tests_mcps
|
||||
- litellm_mapped_tests_integrations
|
||||
- litellm_mapped_tests_litellm_core_utils
|
||||
- litellm_mapped_enterprise_tests
|
||||
|
|
@ -4408,7 +4642,8 @@ workflows:
|
|||
- litellm_assistants_api_testing
|
||||
- auth_ui_unit_tests
|
||||
- db_migration_disable_update_check
|
||||
- e2e_ui_testing
|
||||
- e2e_ui_testing_chromium
|
||||
- e2e_ui_testing_firefox
|
||||
- litellm_proxy_unit_testing_key_generation
|
||||
- litellm_proxy_unit_testing_part1
|
||||
- litellm_proxy_unit_testing_part2
|
||||
|
|
|
|||
|
|
@ -48,7 +48,7 @@ dist/
|
|||
build/
|
||||
*.egg-info/
|
||||
.DS_Store
|
||||
node_modules/
|
||||
**/node_modules
|
||||
*.log
|
||||
.env
|
||||
.env.local
|
||||
|
|
|
|||
|
|
@ -40,38 +40,33 @@ outputs:
|
|||
runs:
|
||||
using: composite
|
||||
steps:
|
||||
- name: Helm | Setup
|
||||
uses: azure/setup-helm@v4
|
||||
with:
|
||||
version: v3.20.0
|
||||
|
||||
- name: Helm | Login
|
||||
shell: bash
|
||||
run: echo ${{ inputs.registry_password }} | helm registry login -u ${{ inputs.registry_username }} --password-stdin ${{ inputs.registry }}
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
|
||||
- name: Helm | Dependency
|
||||
if: inputs.update_dependencies == 'true'
|
||||
shell: bash
|
||||
run: helm dependency update ${{ inputs.path == null && format('{0}/{1}', 'charts', inputs.name) || inputs.path }}
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
- name: Helm | Package
|
||||
shell: bash
|
||||
run: helm package ${{ inputs.path == null && format('{0}/{1}', 'charts', inputs.name) || inputs.path }} --version ${{ inputs.tag }} --app-version ${{ inputs.app_version }}
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
- name: Helm | Push
|
||||
shell: bash
|
||||
run: helm push ${{ inputs.name }}-${{ inputs.tag }}.tgz oci://${{ inputs.registry }}/${{ inputs.repository }}
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
- name: Helm | Logout
|
||||
shell: bash
|
||||
run: helm registry logout ${{ inputs.registry }}
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
- name: Helm | Output
|
||||
id: output
|
||||
shell: bash
|
||||
run: echo "image=${{ inputs.registry }}/${{ inputs.repository }}/${{ inputs.name }}:${{ inputs.tag }}" >> $GITHUB_OUTPUT
|
||||
run: echo "image=${{ inputs.registry }}/${{ inputs.repository }}/${{ inputs.name }}:${{ inputs.tag }}" >> $GITHUB_OUTPUT
|
||||
|
|
|
|||
1
.github/pull_request_template.md
vendored
|
|
@ -9,6 +9,7 @@
|
|||
- [ ] I have Added testing in the [`tests/litellm/`](https://github.com/BerriAI/litellm/tree/main/tests/litellm) directory, **Adding at least 1 test is a hard requirement** - [see details](https://docs.litellm.ai/docs/extras/contributing_code)
|
||||
- [ ] My PR passes all unit tests on [`make test-unit`](https://docs.litellm.ai/docs/extras/contributing_code)
|
||||
- [ ] My PR's scope is as isolated as possible, it only solves 1 specific problem
|
||||
- [ ] I have requested a Greptile review by commenting `@greptileai` and received a **Confidence Score of at least 4/5** before requesting a maintainer review
|
||||
|
||||
## CI (LiteLLM team)
|
||||
|
||||
|
|
|
|||
95
.github/workflows/test-litellm-matrix.yml
vendored
Normal file
|
|
@ -0,0 +1,95 @@
|
|||
name: LiteLLM Unit Tests (Matrix)
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
|
||||
# Cancel in-progress runs for the same PR
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event.pull_request.number || github.ref }}
|
||||
cancel-in-progress: true
|
||||
|
||||
jobs:
|
||||
test:
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 15
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
test-group:
|
||||
# tests/test_litellm split by subdirectory (~560 files total)
|
||||
- name: "llms"
|
||||
path: "tests/test_litellm/llms"
|
||||
workers: 4
|
||||
# tests/test_litellm/proxy split by subdirectory (~180 files total)
|
||||
- name: "proxy-guardrails"
|
||||
path: "tests/test_litellm/proxy/guardrails tests/test_litellm/proxy/management_endpoints tests/test_litellm/proxy/management_helpers"
|
||||
workers: 4
|
||||
- name: "proxy-core"
|
||||
path: "tests/test_litellm/proxy/auth tests/test_litellm/proxy/client tests/test_litellm/proxy/db tests/test_litellm/proxy/hooks tests/test_litellm/proxy/policy_engine"
|
||||
workers: 4
|
||||
- name: "proxy-misc"
|
||||
path: "tests/test_litellm/proxy/_experimental tests/test_litellm/proxy/agent_endpoints tests/test_litellm/proxy/anthropic_endpoints tests/test_litellm/proxy/common_utils tests/test_litellm/proxy/discovery_endpoints tests/test_litellm/proxy/experimental tests/test_litellm/proxy/google_endpoints tests/test_litellm/proxy/health_endpoints tests/test_litellm/proxy/image_endpoints tests/test_litellm/proxy/middleware tests/test_litellm/proxy/openai_files_endpoint tests/test_litellm/proxy/pass_through_endpoints tests/test_litellm/proxy/prompts tests/test_litellm/proxy/public_endpoints tests/test_litellm/proxy/response_api_endpoints tests/test_litellm/proxy/spend_tracking tests/test_litellm/proxy/ui_crud_endpoints tests/test_litellm/proxy/vector_store_endpoints tests/test_litellm/proxy/test_*.py"
|
||||
workers: 4
|
||||
- name: "integrations"
|
||||
path: "tests/test_litellm/integrations"
|
||||
workers: 4
|
||||
- name: "core-utils"
|
||||
path: "tests/test_litellm/litellm_core_utils"
|
||||
workers: 2
|
||||
- name: "other"
|
||||
path: "tests/test_litellm/caching tests/test_litellm/responses tests/test_litellm/secret_managers tests/test_litellm/vector_stores tests/test_litellm/a2a_protocol tests/test_litellm/anthropic_interface tests/test_litellm/completion_extras tests/test_litellm/containers tests/test_litellm/enterprise tests/test_litellm/experimental_mcp_client tests/test_litellm/google_genai tests/test_litellm/images tests/test_litellm/interactions tests/test_litellm/passthrough tests/test_litellm/router_strategy tests/test_litellm/router_utils tests/test_litellm/types"
|
||||
workers: 4
|
||||
- name: "root"
|
||||
path: "tests/test_litellm/test_*.py"
|
||||
workers: 4
|
||||
# tests/proxy_unit_tests split alphabetically (~48 files total)
|
||||
- name: "proxy-unit-a"
|
||||
path: "tests/proxy_unit_tests/test_[a-o]*.py"
|
||||
workers: 2
|
||||
- name: "proxy-unit-b"
|
||||
path: "tests/proxy_unit_tests/test_[p-z]*.py"
|
||||
workers: 2
|
||||
|
||||
name: test (${{ matrix.test-group.name }})
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v4
|
||||
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: "3.12"
|
||||
|
||||
- name: Install Poetry
|
||||
uses: snok/install-poetry@v1
|
||||
|
||||
- name: Cache Poetry dependencies
|
||||
uses: actions/cache@v4
|
||||
with:
|
||||
path: |
|
||||
~/.cache/pypoetry
|
||||
~/.cache/pip
|
||||
.venv
|
||||
key: ${{ runner.os }}-poetry-${{ hashFiles('poetry.lock') }}
|
||||
restore-keys: |
|
||||
${{ runner.os }}-poetry-
|
||||
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
poetry config virtualenvs.in-project true
|
||||
poetry install --with dev,proxy-dev --extras "proxy semantic-router"
|
||||
poetry run pip install pytest-retry==1.6.3 pytest-xdist google-genai==1.22.0 \
|
||||
google-cloud-aiplatform>=1.38 fastapi-offline==1.7.3 python-multipart==0.0.22 openapi-core
|
||||
|
||||
- name: Setup litellm-enterprise
|
||||
run: |
|
||||
cd enterprise && poetry run pip install -e . && cd ..
|
||||
|
||||
- name: Run tests - ${{ matrix.test-group.name }}
|
||||
run: |
|
||||
poetry run pytest ${{ matrix.test-group.path }} \
|
||||
--tb=short -vv \
|
||||
--maxfail=10 \
|
||||
-n ${{ matrix.test-group.workers }} \
|
||||
--durations=20
|
||||
32
.github/workflows/test-litellm-ui-build.yml
vendored
Normal file
|
|
@ -0,0 +1,32 @@
|
|||
name: UI Build Check
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
|
||||
jobs:
|
||||
build-ui:
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 10
|
||||
defaults:
|
||||
run:
|
||||
working-directory: ui/litellm-dashboard
|
||||
|
||||
steps:
|
||||
- name: Checkout repository
|
||||
uses: actions/checkout@v4
|
||||
|
||||
- name: Setup Node.js
|
||||
uses: actions/setup-node@v4
|
||||
with:
|
||||
node-version: "20"
|
||||
cache: "npm"
|
||||
cache-dependency-path: ui/litellm-dashboard/package-lock.json
|
||||
|
||||
- name: Install dependencies
|
||||
run: npm install
|
||||
|
||||
- name: Build
|
||||
run: npm run build
|
||||
8
.github/workflows/test-litellm.yml
vendored
|
|
@ -1,8 +1,12 @@
|
|||
name: LiteLLM Mock Tests (folder - tests/test_litellm)
|
||||
|
||||
# DEPRECATED: This workflow is replaced by test-litellm-matrix.yml which runs
|
||||
# the same tests in parallel across 10 jobs for faster CI times.
|
||||
# Kept for manual debugging only.
|
||||
on:
|
||||
pull_request:
|
||||
branches: [ main ]
|
||||
workflow_dispatch: # Manual trigger only
|
||||
# pull_request:
|
||||
# branches: [ main ]
|
||||
|
||||
jobs:
|
||||
test:
|
||||
|
|
|
|||
1
.gitignore
vendored
|
|
@ -2,6 +2,7 @@
|
|||
.venv
|
||||
.venv_policy_test
|
||||
.env
|
||||
.claude
|
||||
.newenv
|
||||
newenv/*
|
||||
litellm/proxy/myenv/*
|
||||
|
|
|
|||
22
.semgrep/rules/README.md
Normal file
|
|
@ -0,0 +1,22 @@
|
|||
# Custom Semgrep rules for LiteLLM
|
||||
|
||||
Add custom rule YAML files here. Semgrep loads all `.yml`/`.yaml` files under this directory.
|
||||
|
||||
**Run only custom rules (CI / fail on findings):**
|
||||
|
||||
```bash
|
||||
semgrep scan --config .semgrep/rules . --error
|
||||
```
|
||||
|
||||
**Run with registry + custom rules:**
|
||||
|
||||
```bash
|
||||
semgrep scan --config auto --config .semgrep/rules .
|
||||
```
|
||||
|
||||
**Layout:**
|
||||
|
||||
- `python/` – Python-specific rules (security, patterns)
|
||||
- Add more subdirs as needed (e.g. `generic/` for language-agnostic rules)
|
||||
|
||||
See [Semgrep rule syntax](https://semgrep.dev/docs/writing-rules/rule-syntax/).
|
||||
17
.semgrep/rules/python/reliability/unbounded-memory.yml
Normal file
|
|
@ -0,0 +1,17 @@
|
|||
# Unbounded memory growth – data structures without a clear max limit
|
||||
# Can lead to OOM under load.
|
||||
|
||||
rules:
|
||||
- id: unbounded-asyncio-queue
|
||||
message: asyncio.Queue() with no maxsize can grow unbounded. Use asyncio.Queue(maxsize=N) for integrations (e.g. log queues).
|
||||
severity: ERROR
|
||||
languages: [python]
|
||||
pattern-either:
|
||||
- pattern: asyncio.Queue()
|
||||
- pattern: asyncio.Queue(maxsize=0)
|
||||
metadata:
|
||||
category: reliability
|
||||
cwe: "CWE-400: Uncontrolled Resource Consumption"
|
||||
tags: [python, reliability]
|
||||
confidence: HIGH
|
||||
source: https://docs.python.org/3/library/asyncio-queue.html
|
||||
14
.semgrep/rules/python/unbounded-memory.yml
Normal file
|
|
@ -0,0 +1,14 @@
|
|||
# Unbounded memory growth – data structures without a clear max limit
|
||||
# Can lead to OOM under load.
|
||||
|
||||
rules:
|
||||
- id: unbounded-asyncio-queue
|
||||
message: asyncio.Queue() with no maxsize can grow unbounded. Use asyncio.Queue(maxsize=N) for integrations (e.g. log queues).
|
||||
severity: ERROR
|
||||
languages: [python]
|
||||
pattern-either:
|
||||
- pattern: asyncio.Queue()
|
||||
- pattern: asyncio.Queue(maxsize=0)
|
||||
metadata:
|
||||
category: correctness
|
||||
cwe: "CWE-400: Uncontrolled Resource Consumption"
|
||||
|
|
@ -90,6 +90,7 @@ LiteLLM is a unified interface for 100+ LLM providers with two main components:
|
|||
- Pydantic v2 for data validation
|
||||
- Async/await patterns throughout
|
||||
- Type hints required for all public APIs
|
||||
- **Avoid imports within methods** — place all imports at the top of the file (module-level). Inline imports inside functions/methods make dependencies harder to trace and hurt readability. The only exception is avoiding circular imports where absolutely necessary.
|
||||
|
||||
### Testing Strategy
|
||||
- Unit tests in `tests/test_litellm/`
|
||||
|
|
|
|||
|
|
@ -7,11 +7,20 @@ Thank you for your interest in contributing to LiteLLM! We welcome contributions
|
|||
Here are the core requirements for any PR submitted to LiteLLM:
|
||||
|
||||
- [ ] **Sign the Contributor License Agreement (CLA)** - [see details](#contributor-license-agreement-cla)
|
||||
- [ ] **Keep scope isolated** - Your changes should address 1 specific problem at a time
|
||||
|
||||
#### Proxy (Backend) PRs
|
||||
|
||||
- [ ] **Add testing** - Adding at least 1 test is a hard requirement - [see details](#adding-testing)
|
||||
- [ ] **Ensure your PR passes all checks**:
|
||||
- [ ] [Unit Tests](#running-unit-tests) - `make test-unit`
|
||||
- [ ] [Linting / Formatting](#running-linting-and-formatting-checks) - `make lint`
|
||||
- [ ] **Keep scope isolated** - Your changes should address 1 specific problem at a time
|
||||
|
||||
#### UI PRs
|
||||
|
||||
- [ ] **Ensure the UI builds successfully** - `npm run build`
|
||||
- [ ] **Ensure all UI unit tests pass** - `npm run test`
|
||||
- [ ] **Add tests for new components or logic** - If you are adding a new component or new logic, add corresponding tests
|
||||
|
||||
## **Contributor License Agreement (CLA)**
|
||||
|
||||
|
|
@ -245,6 +254,43 @@ docker run \
|
|||
--config /app/config.yaml --detailed_debug
|
||||
```
|
||||
|
||||
## UI Development
|
||||
|
||||
### 1. Setup Your Local UI Development Environment
|
||||
|
||||
```bash
|
||||
# Clone the repo (if you haven't already)
|
||||
git clone https://github.com/YOUR_USERNAME/litellm.git
|
||||
cd litellm
|
||||
|
||||
# Navigate to the UI dashboard directory
|
||||
cd ui/litellm-dashboard
|
||||
|
||||
# Install dependencies
|
||||
npm install
|
||||
|
||||
# Start the development server
|
||||
npm run dev
|
||||
```
|
||||
|
||||
### 2. Adding UI Tests
|
||||
|
||||
If you are adding a **new component** or **new logic**, you must add corresponding tests.
|
||||
|
||||
### 3. Running UI Unit Tests
|
||||
|
||||
```bash
|
||||
npm run test
|
||||
```
|
||||
|
||||
### 4. Building the UI
|
||||
|
||||
Ensure the UI builds successfully before submitting your PR:
|
||||
|
||||
```bash
|
||||
npm run build
|
||||
```
|
||||
|
||||
## Submitting Your PR
|
||||
|
||||
1. **Push your branch**: `git push origin your-feature-branch`
|
||||
|
|
|
|||
36
Dockerfile
|
|
@ -3,6 +3,7 @@ ARG LITELLM_BUILD_IMAGE=cgr.dev/chainguard/wolfi-base
|
|||
|
||||
# Runtime image
|
||||
ARG LITELLM_RUNTIME_IMAGE=cgr.dev/chainguard/wolfi-base
|
||||
|
||||
# Builder stage
|
||||
FROM $LITELLM_BUILD_IMAGE AS builder
|
||||
|
||||
|
|
@ -48,7 +49,22 @@ USER root
|
|||
|
||||
# Install runtime dependencies (libsndfile needed for audio processing on ARM64)
|
||||
RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip libsndfile && \
|
||||
npm install -g npm@latest tar@latest
|
||||
npm install -g npm@latest tar@7.5.7 glob@11.1.0 @isaacs/brace-expansion@5.0.1 && \
|
||||
# SECURITY FIX: npm bundles tar, glob, and brace-expansion at multiple nested
|
||||
# levels inside its dependency tree. `npm install -g <pkg>` only creates a
|
||||
# SEPARATE global package, it does NOT replace npm's internal copies.
|
||||
# We must find and replace EVERY copy inside npm's directory.
|
||||
GLOBAL="$(npm root -g)" && \
|
||||
find "$GLOBAL/npm" -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
done && \
|
||||
find "$GLOBAL/npm" -type d -name "glob" -path "*/node_modules/glob" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/glob" "$d"; \
|
||||
done && \
|
||||
find "$GLOBAL/npm" -type d -name "brace-expansion" -path "*/node_modules/@isaacs/brace-expansion" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/@isaacs/brace-expansion" "$d"; \
|
||||
done && \
|
||||
npm cache clean --force
|
||||
|
||||
WORKDIR /app
|
||||
# Copy the current directory contents into the container at /app
|
||||
|
|
@ -62,10 +78,28 @@ COPY --from=builder /wheels/ /wheels/
|
|||
# Install the built wheel using pip; again using a wildcard if it's the only file
|
||||
RUN pip install *.whl /wheels/* --no-index --find-links=/wheels/ && rm -f *.whl && rm -rf /wheels
|
||||
|
||||
# Replace the nodejs-wheel-binaries bundled node with the system node (fixes CVE-2025-55130)
|
||||
RUN NODEJS_WHEEL_NODE=$(find /usr/lib -path "*/nodejs_wheel/bin/node" 2>/dev/null) && \
|
||||
if [ -n "$NODEJS_WHEEL_NODE" ]; then cp /usr/bin/node "$NODEJS_WHEEL_NODE"; fi
|
||||
|
||||
# Remove test files and keys from dependencies
|
||||
RUN find /usr/lib -type f -path "*/tornado/test/*" -delete && \
|
||||
find /usr/lib -type d -path "*/tornado/test" -delete
|
||||
|
||||
# SECURITY FIX: nodejs-wheel-binaries (pip package used by Prisma) bundles a complete
|
||||
# npm with old vulnerable deps at /usr/lib/python3.*/site-packages/nodejs_wheel/.
|
||||
# Patch every copy of tar, glob, and brace-expansion inside that tree.
|
||||
RUN GLOBAL="$(npm root -g)" && \
|
||||
find /usr/lib -path "*/nodejs_wheel/*/node_modules/tar" -type d | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -path "*/nodejs_wheel/*/node_modules/glob" -type d | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/glob" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -path "*/nodejs_wheel/*/node_modules/@isaacs/brace-expansion" -type d | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/@isaacs/brace-expansion" "$d"; \
|
||||
done
|
||||
|
||||
# Install semantic_router and aurelio-sdk using script
|
||||
# Convert Windows line endings to Unix and make executable
|
||||
RUN sed -i 's/\r$//' docker/install_auto_router.sh && chmod +x docker/install_auto_router.sh && ./docker/install_auto_router.sh
|
||||
|
|
|
|||
46
Makefile
|
|
@ -1,7 +1,9 @@
|
|||
# LiteLLM Makefile
|
||||
# Simple Makefile for running tests and basic development tasks
|
||||
|
||||
.PHONY: help test test-unit test-integration test-unit-helm \
|
||||
.PHONY: help test test-unit test-unit-llms test-unit-proxy-guardrails test-unit-proxy-core test-unit-proxy-misc \
|
||||
test-unit-integrations test-unit-core-utils test-unit-other test-unit-root \
|
||||
test-proxy-unit-a test-proxy-unit-b test-integration test-unit-helm \
|
||||
info lint lint-dev format \
|
||||
install-dev install-proxy-dev install-test-deps \
|
||||
install-helm-unittest check-circular-imports check-import-safety
|
||||
|
|
@ -25,6 +27,16 @@ help:
|
|||
@echo " make check-import-safety - Check import safety"
|
||||
@echo " make test - Run all tests"
|
||||
@echo " make test-unit - Run unit tests (tests/test_litellm)"
|
||||
@echo " make test-unit-llms - Run LLM provider tests (~225 files)"
|
||||
@echo " make test-unit-proxy-guardrails - Run proxy guardrails+mgmt tests (~51 files)"
|
||||
@echo " make test-unit-proxy-core - Run proxy auth+client+db+hooks tests (~52 files)"
|
||||
@echo " make test-unit-proxy-misc - Run proxy misc tests (~77 files)"
|
||||
@echo " make test-unit-integrations - Run integration tests (~60 files)"
|
||||
@echo " make test-unit-core-utils - Run core utils tests (~32 files)"
|
||||
@echo " make test-unit-other - Run other tests (caching, responses, etc., ~69 files)"
|
||||
@echo " make test-unit-root - Run root-level tests (~34 files)"
|
||||
@echo " make test-proxy-unit-a - Run proxy_unit_tests (a-o, ~20 files)"
|
||||
@echo " make test-proxy-unit-b - Run proxy_unit_tests (p-z, ~28 files)"
|
||||
@echo " make test-integration - Run integration tests"
|
||||
@echo " make test-unit-helm - Run helm unit tests"
|
||||
|
||||
|
|
@ -129,6 +141,38 @@ test:
|
|||
test-unit: install-test-deps
|
||||
poetry run pytest tests/test_litellm -x -vv -n 4
|
||||
|
||||
# Matrix test targets (matching CI workflow groups)
|
||||
test-unit-llms: install-test-deps
|
||||
poetry run pytest tests/test_litellm/llms --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-proxy-guardrails: install-test-deps
|
||||
poetry run pytest tests/test_litellm/proxy/guardrails tests/test_litellm/proxy/management_endpoints tests/test_litellm/proxy/management_helpers --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-proxy-core: install-test-deps
|
||||
poetry run pytest tests/test_litellm/proxy/auth tests/test_litellm/proxy/client tests/test_litellm/proxy/db tests/test_litellm/proxy/hooks tests/test_litellm/proxy/policy_engine --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-proxy-misc: install-test-deps
|
||||
poetry run pytest tests/test_litellm/proxy/_experimental tests/test_litellm/proxy/agent_endpoints tests/test_litellm/proxy/anthropic_endpoints tests/test_litellm/proxy/common_utils tests/test_litellm/proxy/discovery_endpoints tests/test_litellm/proxy/experimental tests/test_litellm/proxy/google_endpoints tests/test_litellm/proxy/health_endpoints tests/test_litellm/proxy/image_endpoints tests/test_litellm/proxy/middleware tests/test_litellm/proxy/openai_files_endpoint tests/test_litellm/proxy/pass_through_endpoints tests/test_litellm/proxy/prompts tests/test_litellm/proxy/public_endpoints tests/test_litellm/proxy/response_api_endpoints tests/test_litellm/proxy/spend_tracking tests/test_litellm/proxy/ui_crud_endpoints tests/test_litellm/proxy/vector_store_endpoints tests/test_litellm/proxy/test_*.py --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-integrations: install-test-deps
|
||||
poetry run pytest tests/test_litellm/integrations --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-core-utils: install-test-deps
|
||||
poetry run pytest tests/test_litellm/litellm_core_utils --tb=short -vv -n 2 --durations=20
|
||||
|
||||
test-unit-other: install-test-deps
|
||||
poetry run pytest tests/test_litellm/caching tests/test_litellm/responses tests/test_litellm/secret_managers tests/test_litellm/vector_stores tests/test_litellm/a2a_protocol tests/test_litellm/anthropic_interface tests/test_litellm/completion_extras tests/test_litellm/containers tests/test_litellm/enterprise tests/test_litellm/experimental_mcp_client tests/test_litellm/google_genai tests/test_litellm/images tests/test_litellm/interactions tests/test_litellm/passthrough tests/test_litellm/router_strategy tests/test_litellm/router_utils tests/test_litellm/types --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-root: install-test-deps
|
||||
poetry run pytest tests/test_litellm/test_*.py --tb=short -vv -n 4 --durations=20
|
||||
|
||||
# Proxy unit tests (tests/proxy_unit_tests split alphabetically)
|
||||
test-proxy-unit-a: install-test-deps
|
||||
poetry run pytest tests/proxy_unit_tests/test_[a-o]*.py --tb=short -vv -n 2 --durations=20
|
||||
|
||||
test-proxy-unit-b: install-test-deps
|
||||
poetry run pytest tests/proxy_unit_tests/test_[p-z]*.py --tb=short -vv -n 2 --durations=20
|
||||
|
||||
test-integration:
|
||||
poetry run pytest tests/ -k "not test_litellm"
|
||||
|
||||
|
|
|
|||
|
|
@ -309,7 +309,7 @@ Support for more providers. Missing a provider or LLM Platform, raise a [feature
|
|||
| [Deepgram (`deepgram`)](https://docs.litellm.ai/docs/providers/deepgram) | ✅ | ✅ | ✅ | | | ✅ | | | | |
|
||||
| [DeepInfra (`deepinfra`)](https://docs.litellm.ai/docs/providers/deepinfra) | ✅ | ✅ | ✅ | | | | | | | |
|
||||
| [Deepseek (`deepseek`)](https://docs.litellm.ai/docs/providers/deepseek) | ✅ | ✅ | ✅ | | | | | | | |
|
||||
| [ElevenLabs (`elevenlabs`)](https://docs.litellm.ai/docs/providers/elevenlabs) | ✅ | ✅ | ✅ | | | | ✅ | | | |
|
||||
| [ElevenLabs (`elevenlabs`)](https://docs.litellm.ai/docs/providers/elevenlabs) | ✅ | ✅ | ✅ | | | ✅ | ✅ | | | |
|
||||
| [Empower (`empower`)](https://docs.litellm.ai/docs/providers/empower) | ✅ | ✅ | ✅ | | | | | | | |
|
||||
| [Fal AI (`fal_ai`)](https://docs.litellm.ai/docs/providers/fal_ai) | ✅ | ✅ | ✅ | | ✅ | | | | | |
|
||||
| [Featherless AI (`featherless_ai`)](https://docs.litellm.ai/docs/providers/featherless_ai) | ✅ | ✅ | ✅ | | | | | | | |
|
||||
|
|
|
|||
|
|
@ -1,3 +1,36 @@
|
|||
ignore:
|
||||
- vulnerability: CVE-2026-22184
|
||||
reason: no fixed zlib package is available yet in the Wolfi repositories, so this is ignored temporarily until an upstream release exists
|
||||
# Wolfi base image: Python 3.13 and Node from apk have no fixed builds in Wolfi yet / not applicable
|
||||
- vulnerability: CVE-2025-55130
|
||||
reason: Node in Wolfi apk; only used for Admin UI build/prisma
|
||||
- vulnerability: CVE-2025-59465
|
||||
reason: Node in Wolfi apk; only used for Admin UI build/prisma
|
||||
- vulnerability: CVE-2025-55131
|
||||
reason: Node in Wolfi apk; only used for Admin UI build/prisma
|
||||
- vulnerability: CVE-2025-59466
|
||||
reason: Node in Wolfi apk; only used for Admin UI build/prisma
|
||||
- vulnerability: CVE-2026-21637
|
||||
reason: Node in Wolfi apk; only used for Admin UI build/prisma
|
||||
- vulnerability: CVE-2025-55132
|
||||
reason: Node in Wolfi apk; only used for Admin UI build/prisma
|
||||
- vulnerability: GHSA-hx9q-6w63-j58v
|
||||
reason: orjson dumps recursion; allowlisted
|
||||
- vulnerability: GHSA-73rr-hh4g-fpgx
|
||||
reason: diff npm transitive dep; override in package.json, allowlisted
|
||||
- vulnerability: CVE-2026-0865
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
- vulnerability: CVE-2025-15282
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
- vulnerability: CVE-2026-0672
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
- vulnerability: CVE-2025-15366
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
- vulnerability: CVE-2025-15367
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
- vulnerability: CVE-2025-11468
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
- vulnerability: CVE-2025-12781
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
- vulnerability: CVE-2026-1299
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
|
|
|
|||
|
|
@ -140,12 +140,14 @@ run_grype_scans() {
|
|||
"GHSA-34x7-hfp2-rc4v" # node-tar hardlink path traversal - not applicable, tar CLI not exposed in application code
|
||||
"GHSA-r6q2-hw4h-h46w" # node-tar not used by application runtime, Linux-only container, not affect by macOS APFS-specific exploit
|
||||
"GHSA-8rrh-rw8j-w5fx" # wheel is from chainguard and will be handled by then TODO: Remove this after Chainguard updates the wheel
|
||||
"CVE-2025-59465" # We do not use Node in application runtime, only used for building Admin UI
|
||||
"CVE-2025-55131" # We do not use Node in application runtime, only used for building Admin UI
|
||||
"CVE-2025-59466" # We do not use Node in application runtime, only used for building Admin UI
|
||||
"CVE-2025-55130" # We do not use Node in application runtime, only used for building Admin UI
|
||||
"CVE-2025-59467" # We do not use Node in application runtime, only used for building Admin UI
|
||||
"CVE-2026-21637" # We do not use Node in application runtime, only used for building Admin UI
|
||||
"CVE-2025-59465" # Node only used for Admin UI build/prisma
|
||||
"CVE-2025-55131" # Node only used for Admin UI build/prisma
|
||||
"CVE-2025-59466" # Node only used for Admin UI build/prisma
|
||||
"CVE-2025-55130" # Node only used for Admin UI build/prisma
|
||||
"CVE-2025-59467" # Node only used for Admin UI build/prisma
|
||||
"CVE-2026-21637" # Node only used for Admin UI build/prisma
|
||||
"CVE-2025-55132" # Node only used for Admin UI build/prisma
|
||||
"GHSA-hx9q-6w63-j58v" # orjson dumps recursion; allowlisted
|
||||
"CVE-2025-15281" # No fix available yet
|
||||
"CVE-2026-0865" # No fix available yet
|
||||
"CVE-2025-15282" # No fix available yet
|
||||
|
|
@ -155,6 +157,7 @@ run_grype_scans() {
|
|||
"CVE-2025-12781" # No fix available yet
|
||||
"CVE-2025-11468" # No fix available yet
|
||||
"CVE-2026-1299" # Python 3.13 email module header injection - not applicable, LiteLLM doesn't use BytesGenerator for email serialization
|
||||
"CVE-2026-0775" # npm cli incorrect permission assignment - no fix available yet, npm is only used at build/prisma-generate time
|
||||
)
|
||||
|
||||
# Build JSON array of allowlisted CVE IDs for jq
|
||||
|
|
|
|||
114
cookbook/livekit_agent_sdk/README.md
Normal file
|
|
@ -0,0 +1,114 @@
|
|||
# LiveKit Voice Agent with LiteLLM Gateway
|
||||
|
||||
Simple example showing how to use LiveKit's xAI realtime plugin with LiteLLM as a proxy. This lets you switch between xAI, OpenAI, and Azure realtime APIs without changing your code.
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Install dependencies
|
||||
|
||||
```bash
|
||||
pip install livekit-agents[xai] websockets
|
||||
```
|
||||
|
||||
### 2. Start LiteLLM proxy
|
||||
|
||||
```bash
|
||||
# With xAI
|
||||
export XAI_API_KEY="your-xai-key"
|
||||
litellm --config config.yaml --port 4000
|
||||
```
|
||||
|
||||
### 3. Run the voice agent
|
||||
|
||||
```bash
|
||||
python main.py
|
||||
```
|
||||
|
||||
Type your message and get a voice response from Grok!
|
||||
|
||||
## Configuration
|
||||
|
||||
Set these environment variables if needed:
|
||||
|
||||
```bash
|
||||
export LITELLM_PROXY_URL="http://localhost:4000"
|
||||
export LITELLM_API_KEY="sk-1234"
|
||||
export LITELLM_MODEL="grok-voice-agent"
|
||||
```
|
||||
|
||||
Or use the defaults - connects to `http://localhost:4000` by default.
|
||||
|
||||
## Example Config File
|
||||
|
||||
Create a `config.yaml` with your realtime models:
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: grok-voice-agent
|
||||
litellm_params:
|
||||
model: xai/grok-2-vision-1212
|
||||
api_key: os.environ/XAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
|
||||
- model_name: openai-voice-agent
|
||||
litellm_params:
|
||||
model: gpt-4o-realtime-preview
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
|
||||
general_settings:
|
||||
master_key: sk-1234
|
||||
```
|
||||
|
||||
Then start: `litellm --config config.yaml --port 4000`
|
||||
|
||||
## How It Works
|
||||
|
||||
LiveKit's xAI plugin connects through LiteLLM proxy by setting `base_url`:
|
||||
|
||||
```python
|
||||
from livekit.plugins import xai
|
||||
|
||||
model = xai.realtime.RealtimeModel(
|
||||
voice="ara",
|
||||
api_key="sk-1234", # LiteLLM proxy key
|
||||
base_url="http://localhost:4000", # Point to LiteLLM
|
||||
)
|
||||
```
|
||||
|
||||
## Switching Providers
|
||||
|
||||
Just change the model in your config - no code changes needed:
|
||||
|
||||
**xAI Grok:**
|
||||
```yaml
|
||||
model: xai/grok-2-vision-1212
|
||||
```
|
||||
|
||||
**OpenAI:**
|
||||
```yaml
|
||||
model: gpt-4o-realtime-preview
|
||||
```
|
||||
|
||||
**Azure OpenAI:**
|
||||
```yaml
|
||||
model: azure/gpt-4o-realtime-preview
|
||||
api_base: https://your-endpoint.openai.azure.com/
|
||||
```
|
||||
|
||||
## Why Use LiteLLM?
|
||||
|
||||
- ✅ **Switch providers** without changing agent code
|
||||
- ✅ **Cost tracking** across all voice sessions
|
||||
- ✅ **Rate limiting** and budgets
|
||||
- ✅ **Load balancing** across multiple API keys
|
||||
- ✅ **Fallbacks** to backup models
|
||||
|
||||
## Learn More
|
||||
|
||||
- [LiveKit xAI Realtime Tutorial](/docs/tutorials/livekit_xai_realtime)
|
||||
- [xAI Realtime Docs](/docs/providers/xai_realtime)
|
||||
- [LiveKit Agents Documentation](https://docs.livekit.io/agents/)
|
||||
- [LiteLLM Realtime API](/docs/realtime)
|
||||
21
cookbook/livekit_agent_sdk/config.example.yaml
Normal file
|
|
@ -0,0 +1,21 @@
|
|||
model_list:
|
||||
- model_name: grok-voice-agent
|
||||
litellm_params:
|
||||
model: xai/grok-2-vision-1212
|
||||
api_key: os.environ/XAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
|
||||
- model_name: openai-voice-agent
|
||||
litellm_params:
|
||||
model: gpt-4o-realtime-preview
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
|
||||
litellm_settings:
|
||||
drop_params: True
|
||||
telemetry: False
|
||||
|
||||
general_settings:
|
||||
master_key: sk-1234 # Change this to a secure key
|
||||
112
cookbook/livekit_agent_sdk/main.py
Normal file
|
|
@ -0,0 +1,112 @@
|
|||
"""
|
||||
Simple xAI Voice Agent using LiveKit SDK with LiteLLM Gateway
|
||||
|
||||
This example shows how to use LiveKit's xAI realtime plugin through LiteLLM proxy.
|
||||
LiteLLM acts as a unified interface, allowing you to switch between xAI, OpenAI,
|
||||
and Azure realtime APIs without changing your agent code.
|
||||
"""
|
||||
import asyncio
|
||||
import json
|
||||
import os
|
||||
import websockets
|
||||
|
||||
# Configuration
|
||||
PROXY_URL = os.getenv("LITELLM_PROXY_URL", "http://localhost:4000")
|
||||
API_KEY = os.getenv("LITELLM_API_KEY", "sk-1234")
|
||||
MODEL = os.getenv("LITELLM_MODEL", "grok-voice-agent")
|
||||
|
||||
|
||||
async def run_voice_agent():
|
||||
"""
|
||||
Simple voice agent that:
|
||||
1. Connects to xAI realtime API through LiteLLM proxy
|
||||
2. Sends a user message
|
||||
3. Streams back the response
|
||||
"""
|
||||
|
||||
url = f"ws://{PROXY_URL.replace('http://', '').replace('https://', '')}/v1/realtime?model={MODEL}"
|
||||
headers = {"Authorization": f"Bearer {API_KEY}"}
|
||||
|
||||
print(f"🎙️ Connecting to voice agent...")
|
||||
print(f" Model: {MODEL}")
|
||||
print(f" Proxy: {PROXY_URL}")
|
||||
print()
|
||||
|
||||
async with websockets.connect(url, additional_headers=headers) as ws:
|
||||
# Receive initial connection event
|
||||
initial = json.loads(await ws.recv())
|
||||
print(f"✅ Connected! Event: {initial['type']}\n")
|
||||
|
||||
# Get user input
|
||||
user_message = input("💬 Your message: ").strip()
|
||||
if not user_message:
|
||||
user_message = "Tell me a fun fact about AI!"
|
||||
|
||||
print(f"\n🤖 Sending to {MODEL}...\n")
|
||||
|
||||
# Send user message
|
||||
await ws.send(json.dumps({
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{"type": "input_text", "text": user_message}]
|
||||
}
|
||||
}))
|
||||
|
||||
# Request response
|
||||
await ws.send(json.dumps({
|
||||
"type": "response.create",
|
||||
"response": {"modalities": ["text", "audio"]}
|
||||
}))
|
||||
|
||||
# Stream response
|
||||
print("🎤 Response: ", end='', flush=True)
|
||||
transcript = []
|
||||
|
||||
try:
|
||||
while True:
|
||||
msg = await asyncio.wait_for(ws.recv(), timeout=15.0)
|
||||
event = json.loads(msg)
|
||||
|
||||
# Capture transcript deltas
|
||||
if event['type'] == 'response.output_audio_transcript.delta':
|
||||
delta = event.get('delta', '')
|
||||
if delta:
|
||||
print(delta, end='', flush=True)
|
||||
transcript.append(delta)
|
||||
|
||||
# Done when response completes
|
||||
elif event['type'] == 'response.done':
|
||||
break
|
||||
|
||||
except asyncio.TimeoutError:
|
||||
pass
|
||||
|
||||
print("\n")
|
||||
|
||||
if transcript:
|
||||
print(f"✅ Complete response: {''.join(transcript)}")
|
||||
|
||||
await ws.close()
|
||||
|
||||
|
||||
def main():
|
||||
"""Run the voice agent"""
|
||||
print("=" * 70)
|
||||
print("LiveKit xAI Voice Agent via LiteLLM Proxy")
|
||||
print("=" * 70)
|
||||
print()
|
||||
|
||||
try:
|
||||
asyncio.run(run_voice_agent())
|
||||
except KeyboardInterrupt:
|
||||
print("\n\n👋 Goodbye!")
|
||||
except Exception as e:
|
||||
print(f"\n❌ Error: {e}")
|
||||
print("\nMake sure LiteLLM proxy is running:")
|
||||
print(f" litellm --config config.yaml --port 4000")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
2
cookbook/livekit_agent_sdk/requirements.txt
Normal file
|
|
@ -0,0 +1,2 @@
|
|||
livekit-agents[xai]>=1.3.12
|
||||
websockets>=15.0.1
|
||||
|
|
@ -16,10 +16,14 @@ Usage:
|
|||
import asyncio
|
||||
import base64
|
||||
import json
|
||||
import os
|
||||
import pyaudio
|
||||
import websockets
|
||||
from typing import Optional
|
||||
|
||||
# Bounded queue size for audio chunks (configurable via env to avoid unbounded memory)
|
||||
AUDIO_QUEUE_MAXSIZE = int(os.getenv("LITELLM_ASYNCIO_QUEUE_MAXSIZE", 10_000))
|
||||
|
||||
# Audio configuration (matching Nova Sonic requirements)
|
||||
INPUT_SAMPLE_RATE = 16000 # Nova Sonic expects 16kHz input
|
||||
OUTPUT_SAMPLE_RATE = 24000 # Nova Sonic outputs 24kHz
|
||||
|
|
@ -40,7 +44,7 @@ class RealtimeClient:
|
|||
self.api_key = api_key
|
||||
self.ws: Optional[websockets.WebSocketClientProtocol] = None
|
||||
self.is_active = False
|
||||
self.audio_queue = asyncio.Queue()
|
||||
self.audio_queue = asyncio.Queue(maxsize=AUDIO_QUEUE_MAXSIZE)
|
||||
self.pyaudio = pyaudio.PyAudio()
|
||||
self.input_stream = None
|
||||
self.output_stream = None
|
||||
|
|
|
|||
|
|
@ -26,6 +26,10 @@ version: 1.1.0
|
|||
# It is recommended to use it with quotes.
|
||||
appVersion: v1.80.12
|
||||
|
||||
annotations:
|
||||
org.opencontainers.image.source: "https://github.com/BerriAI/litellm"
|
||||
org.opencontainers.image.url: "https://docs.litellm.ai/"
|
||||
|
||||
dependencies:
|
||||
- name: "postgresql"
|
||||
version: ">=13.3.0"
|
||||
|
|
|
|||
|
|
@ -6,7 +6,18 @@ WORKDIR /app
|
|||
|
||||
# Install Node.js and npm (adjust version as needed)
|
||||
RUN apt-get update && apt-get install -y nodejs npm && \
|
||||
npm install -g npm@latest tar@latest
|
||||
npm install -g npm@latest tar@7.5.7 glob@11.1.0 @isaacs/brace-expansion@5.0.1 && \
|
||||
GLOBAL="$(npm root -g)" && \
|
||||
find "$GLOBAL/npm" -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
done && \
|
||||
find "$GLOBAL/npm" -type d -name "glob" -path "*/node_modules/glob" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/glob" "$d"; \
|
||||
done && \
|
||||
find "$GLOBAL/npm" -type d -name "brace-expansion" -path "*/node_modules/@isaacs/brace-expansion" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/@isaacs/brace-expansion" "$d"; \
|
||||
done && \
|
||||
npm cache clean --force
|
||||
|
||||
# Copy the UI source into the container
|
||||
COPY ./ui/litellm-dashboard /app/ui/litellm-dashboard
|
||||
|
|
|
|||
|
|
@ -50,7 +50,18 @@ USER root
|
|||
|
||||
# Install runtime dependencies
|
||||
RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip libsndfile && \
|
||||
npm install -g npm@latest tar@latest
|
||||
npm install -g npm@latest tar@7.5.7 glob@11.1.0 @isaacs/brace-expansion@5.0.1 && \
|
||||
GLOBAL="$(npm root -g)" && \
|
||||
find "$GLOBAL/npm" -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
done && \
|
||||
find "$GLOBAL/npm" -type d -name "glob" -path "*/node_modules/glob" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/glob" "$d"; \
|
||||
done && \
|
||||
find "$GLOBAL/npm" -type d -name "brace-expansion" -path "*/node_modules/@isaacs/brace-expansion" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/@isaacs/brace-expansion" "$d"; \
|
||||
done && \
|
||||
npm cache clean --force
|
||||
|
||||
WORKDIR /app
|
||||
# Copy the current directory contents into the container at /app
|
||||
|
|
@ -64,6 +75,20 @@ COPY --from=builder /wheels/ /wheels/
|
|||
# Install the built wheel using pip; again using a wildcard if it's the only file
|
||||
RUN pip install *.whl /wheels/* --no-index --find-links=/wheels/ && rm -f *.whl && rm -rf /wheels
|
||||
|
||||
# SECURITY FIX: nodejs-wheel-binaries (pip package used by Prisma) bundles a complete
|
||||
# npm with old vulnerable deps at /usr/lib/python3.*/site-packages/nodejs_wheel/.
|
||||
# Patch every copy of tar, glob, and brace-expansion inside that tree.
|
||||
RUN GLOBAL="$(npm root -g)" && \
|
||||
find /usr/lib -path "*/nodejs_wheel/*/node_modules/tar" -type d | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -path "*/nodejs_wheel/*/node_modules/glob" -type d | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/glob" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -path "*/nodejs_wheel/*/node_modules/@isaacs/brace-expansion" -type d | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/@isaacs/brace-expansion" "$d"; \
|
||||
done
|
||||
|
||||
# Install semantic_router and aurelio-sdk using script
|
||||
# Convert Windows line endings to Unix and make executable
|
||||
RUN sed -i 's/\r$//' docker/install_auto_router.sh && chmod +x docker/install_auto_router.sh && ./docker/install_auto_router.sh
|
||||
|
|
|
|||
|
|
@ -62,7 +62,18 @@ RUN apt-get update && apt-get install -y --no-install-recommends \
|
|||
nodejs \
|
||||
npm \
|
||||
&& rm -rf /var/lib/apt/lists/* \
|
||||
&& npm install -g npm@latest tar@latest
|
||||
&& npm install -g npm@latest tar@7.5.7 glob@11.1.0 @isaacs/brace-expansion@5.0.1 \
|
||||
&& GLOBAL="$(npm root -g)" \
|
||||
&& find "$GLOBAL/npm" -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
done \
|
||||
&& find "$GLOBAL/npm" -type d -name "glob" -path "*/node_modules/glob" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/glob" "$d"; \
|
||||
done \
|
||||
&& find "$GLOBAL/npm" -type d -name "brace-expansion" -path "*/node_modules/@isaacs/brace-expansion" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/@isaacs/brace-expansion" "$d"; \
|
||||
done \
|
||||
&& npm cache clean --force
|
||||
|
||||
WORKDIR /app
|
||||
|
||||
|
|
@ -80,6 +91,20 @@ RUN pip install --no-cache-dir *.whl /wheels/* --no-index --find-links=/wheels/
|
|||
rm -f *.whl && \
|
||||
rm -rf /wheels
|
||||
|
||||
# SECURITY FIX: nodejs-wheel-binaries (pip package used by Prisma) bundles a complete
|
||||
# npm with old vulnerable deps at /usr/lib/python3.*/site-packages/nodejs_wheel/.
|
||||
# Patch every copy of tar, glob, and brace-expansion inside that tree.
|
||||
RUN GLOBAL="$(npm root -g)" && \
|
||||
find /usr/lib -path "*/nodejs_wheel/*/node_modules/tar" -type d | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -path "*/nodejs_wheel/*/node_modules/glob" -type d | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/glob" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -path "*/nodejs_wheel/*/node_modules/@isaacs/brace-expansion" -type d | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/@isaacs/brace-expansion" "$d"; \
|
||||
done
|
||||
|
||||
# Generate prisma client and set permissions
|
||||
# Convert Windows line endings to Unix for entrypoint scripts
|
||||
RUN prisma generate && \
|
||||
|
|
|
|||
|
|
@ -47,7 +47,6 @@ RUN mkdir -p /var/lib/litellm/ui && \
|
|||
if [ -f "/app/enterprise/enterprise_ui/enterprise_colors.json" ]; then \
|
||||
cp /app/enterprise/enterprise_ui/enterprise_colors.json ./ui_colors.json; \
|
||||
fi && \
|
||||
rm -f package-lock.json && \
|
||||
npm install --legacy-peer-deps && \
|
||||
npm run build && \
|
||||
cp -r /app/ui/litellm-dashboard/out/* /var/lib/litellm/ui/ && \
|
||||
|
|
@ -60,7 +59,8 @@ RUN mkdir -p /var/lib/litellm/ui && \
|
|||
mkdir -p "$folder_name" && \
|
||||
mv "$html_file" "$folder_name/index.html"; \
|
||||
fi; \
|
||||
done ) && \
|
||||
done && \
|
||||
touch .litellm_ui_ready ) && \
|
||||
cd /app/ui/litellm-dashboard && rm -rf ./out
|
||||
|
||||
# Build litellm wheel and place it in wheels dir (replace any PyPI wheels)
|
||||
|
|
@ -105,7 +105,18 @@ RUN for i in 1 2 3; do \
|
|||
&& for i in 1 2 3; do \
|
||||
apk add --no-cache python3 py3-pip bash openssl tzdata nodejs npm supervisor && break || sleep 5; \
|
||||
done \
|
||||
&& npm install -g npm@latest tar@latest
|
||||
&& npm install -g npm@latest tar@7.5.7 glob@11.1.0 @isaacs/brace-expansion@5.0.1 \
|
||||
&& GLOBAL="$(npm root -g)" \
|
||||
&& find "$GLOBAL/npm" -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
done \
|
||||
&& find "$GLOBAL/npm" -type d -name "glob" -path "*/node_modules/glob" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/glob" "$d"; \
|
||||
done \
|
||||
&& find "$GLOBAL/npm" -type d -name "brace-expansion" -path "*/node_modules/@isaacs/brace-expansion" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/@isaacs/brace-expansion" "$d"; \
|
||||
done \
|
||||
&& npm cache clean --force
|
||||
|
||||
# Copy artifacts from builder
|
||||
COPY --from=builder /app/requirements.txt /app/requirements.txt
|
||||
|
|
@ -147,6 +158,20 @@ RUN pip install --no-index --find-links=/wheels/ -r requirements.txt && \
|
|||
fi; \
|
||||
fi
|
||||
|
||||
# SECURITY FIX: nodejs-wheel-binaries (pip package used by Prisma) bundles a complete
|
||||
# npm with old vulnerable deps at /usr/lib/python3.*/site-packages/nodejs_wheel/.
|
||||
# Patch every copy of tar, glob, and brace-expansion inside that tree.
|
||||
RUN GLOBAL="$(npm root -g)" && \
|
||||
find /usr/lib -path "*/nodejs_wheel/*/node_modules/tar" -type d | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -path "*/nodejs_wheel/*/node_modules/glob" -type d | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/glob" "$d"; \
|
||||
done && \
|
||||
find /usr/lib -path "*/nodejs_wheel/*/node_modules/@isaacs/brace-expansion" -type d | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/@isaacs/brace-expansion" "$d"; \
|
||||
done
|
||||
|
||||
# Permissions, cleanup, and Prisma prep
|
||||
# Convert Windows line endings to Unix for entrypoint scripts
|
||||
RUN sed -i 's/\r$//' docker/entrypoint.sh && \
|
||||
|
|
|
|||
|
|
@ -70,9 +70,12 @@ docker compose -f docker-compose.yml -f docker-compose.hardened.yml up -d
|
|||
|
||||
This setup:
|
||||
- Builds from `docker/Dockerfile.non_root` with Prisma engines and Node toolchain baked into the image.
|
||||
- Runs the proxy as a non-root user with a read-only rootfs and only two writable tmpfs mounts:
|
||||
- Runs the proxy as a non-root user with a read-only rootfs and only writable tmpfs mounts:
|
||||
- `/app/cache` (Prisma/NPM cache; backing `PRISMA_BINARY_CACHE_DIR`, `NPM_CONFIG_CACHE`, `XDG_CACHE_HOME`)
|
||||
- `/app/migrations` (Prisma migration workspace; backing `LITELLM_MIGRATION_DIR`)
|
||||
- Pre-builds and serves the admin UI from read-only paths:
|
||||
- `/var/lib/litellm/ui` (pre-restructured Next.js UI with `.litellm_ui_ready` marker)
|
||||
- `/var/lib/litellm/assets` (UI logos and assets)
|
||||
- Routes all outbound traffic through a local Squid proxy that denies egress, so Prisma migrations must use the cached CLI and engines.
|
||||
|
||||
You should also verify offline Prisma behaviour with:
|
||||
|
|
|
|||
730
docs/my-website/blog/claude_opus_4_6/index.md
Normal file
|
|
@ -0,0 +1,730 @@
|
|||
---
|
||||
slug: claude_opus_4_6
|
||||
title: "Day 0 Support: Claude Opus 4.6"
|
||||
date: 2026-02-05T10:00:00
|
||||
authors:
|
||||
- name: Sameer Kankute
|
||||
title: SWE @ LiteLLM (LLM Translation)
|
||||
url: https://www.linkedin.com/in/sameer-kankute/
|
||||
image_url: https://pbs.twimg.com/profile_images/2001352686994907136/ONgNuSk5_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
- name: Krrish Dholakia
|
||||
title: "CEO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
description: "Day 0 support for Claude Opus 4.6 on LiteLLM AI Gateway - use across Anthropic, Azure, Vertex AI, and Bedrock."
|
||||
tags: [anthropic, claude, opus 4.6]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
LiteLLM now supports Claude Opus 4.6 on Day 0. Use it across Anthropic, Azure, Vertex AI, and Bedrock through the LiteLLM AI Gateway.
|
||||
|
||||
## Docker Image
|
||||
|
||||
```bash
|
||||
docker pull ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6
|
||||
```
|
||||
|
||||
## Usage - Anthropic
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-6
|
||||
litellm_params:
|
||||
model: anthropic/claude-opus-4-6
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e ANTHROPIC_API_KEY=$ANTHROPIC_API_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Azure
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-6
|
||||
litellm_params:
|
||||
model: azure_ai/claude-opus-4-6
|
||||
api_key: os.environ/AZURE_AI_API_KEY
|
||||
api_base: os.environ/AZURE_AI_API_BASE # https://<resource>.services.ai.azure.com
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e AZURE_AI_API_KEY=$AZURE_AI_API_KEY \
|
||||
-e AZURE_AI_API_BASE=$AZURE_AI_API_BASE \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Vertex AI
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-6
|
||||
litellm_params:
|
||||
model: vertex_ai/claude-opus-4-6
|
||||
vertex_project: os.environ/VERTEX_PROJECT
|
||||
vertex_location: us-east5
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e VERTEX_PROJECT=$VERTEX_PROJECT \
|
||||
-e GOOGLE_APPLICATION_CREDENTIALS=/app/credentials.json \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
-v $(pwd)/credentials.json:/app/credentials.json \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Bedrock
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-6
|
||||
litellm_params:
|
||||
model: bedrock/anthropic.claude-opus-4-6-v1:0
|
||||
aws_access_key_id: os.environ/AWS_ACCESS_KEY_ID
|
||||
aws_secret_access_key: os.environ/AWS_SECRET_ACCESS_KEY
|
||||
aws_region_name: us-east-1
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e AWS_ACCESS_KEY_ID=$AWS_ACCESS_KEY_ID \
|
||||
-e AWS_SECRET_ACCESS_KEY=$AWS_SECRET_ACCESS_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Advanced Features
|
||||
|
||||
### Compaction
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="completions" label="/chat/completions">
|
||||
|
||||
Litellm supports enabling compaction for the new claude-opus-4-6.
|
||||
|
||||
**Enabling Compaction**
|
||||
|
||||
To enable compaction, add the `context_management` parameter with the `compact_20260112` edit type:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What is the weather in San Francisco?"
|
||||
}
|
||||
],
|
||||
"context_management": {
|
||||
"edits": [
|
||||
{
|
||||
"type": "compact_20260112"
|
||||
}
|
||||
]
|
||||
},
|
||||
"max_tokens": 100
|
||||
}'
|
||||
```
|
||||
All the parameters supported for context_management by anthropic are supported and can be directly added. Litellm automatically adds the `compact-2026-01-12` beta header in the request.
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="messages" label="/v1/messages">
|
||||
|
||||
Enable compaction to reduce context size while preserving key information. LiteLLM automatically adds the `compact-2026-01-12` beta header when compaction is enabled.
|
||||
|
||||
:::info
|
||||
**Provider Support:** Compaction is supported on Anthropic, Azure AI, and Vertex AI. It is **not supported** on Bedrock (Invoke or Converse APIs).
|
||||
:::
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'x-api-key: sk-12345' \
|
||||
--header 'content-type: application/json' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"max_tokens": 4096,
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Hi"
|
||||
}
|
||||
],
|
||||
"context_management": {
|
||||
"edits": [
|
||||
{
|
||||
"type": "compact_20260112"
|
||||
}
|
||||
]
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
||||
**Response with Compaction Block**
|
||||
|
||||
The response will include the compaction summary in `provider_specific_fields.compaction_blocks`:
|
||||
|
||||
```json
|
||||
{
|
||||
"id": "chatcmpl-a6c105a3-4b25-419e-9551-c800633b6cb2",
|
||||
"created": 1770357619,
|
||||
"model": "claude-opus-4-6",
|
||||
"object": "chat.completion",
|
||||
"choices": [
|
||||
{
|
||||
"finish_reason": "length",
|
||||
"index": 0,
|
||||
"message": {
|
||||
"content": "I don't have access to real-time data, so I can't provide the current weather in San Francisco. To get up-to-date weather information, I'd recommend checking:\n\n- **Weather websites** like weather.com, accuweather.com, or wunderground.com\n- **Search engines** – just Google \"San Francisco weather\"\n- **Weather apps** on your phone (e.g., Apple Weather, Google Weather)\n- **National",
|
||||
"role": "assistant",
|
||||
"provider_specific_fields": {
|
||||
"compaction_blocks": [
|
||||
{
|
||||
"type": "compaction",
|
||||
"content": "Summary of the conversation: The user requested help building a web scraper..."
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
],
|
||||
"usage": {
|
||||
"completion_tokens": 100,
|
||||
"prompt_tokens": 86,
|
||||
"total_tokens": 186
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Using Compaction Blocks in Follow-up Requests**
|
||||
|
||||
To continue the conversation with compaction, include the compaction block in the assistant message's `provider_specific_fields`:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "How can I build a web scraper?"
|
||||
},
|
||||
{
|
||||
"role": "assistant",
|
||||
"content": [
|
||||
{
|
||||
"type": "text",
|
||||
"text": "Certainly! To build a basic web scraper, you'll typically use a programming language like Python along with libraries such as `requests` (for fetching web pages) and `BeautifulSoup` (for parsing HTML). Here's a basic example:\n\n```python\nimport requests\nfrom bs4 import BeautifulSoup\n\nurl = 'https://example.com'\nresponse = requests.get(url)\nsoup = BeautifulSoup(response.text, 'html.parser')\n\n# Extract and print all text\ntext = soup.get_text()\nprint(text)\n```\n\nLet me know what you're interested in scraping or if you need help with a specific website!"
|
||||
}
|
||||
],
|
||||
"provider_specific_fields": {
|
||||
"compaction_blocks": [
|
||||
{
|
||||
"type": "compaction",
|
||||
"content": "Summary of the conversation: The user asked how to build a web scraper, and the assistant gave an overview using Python with requests and BeautifulSoup."
|
||||
}
|
||||
]
|
||||
}
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"content": "How do I use it to scrape product prices?"
|
||||
}
|
||||
],
|
||||
"context_management": {
|
||||
"edits": [
|
||||
{
|
||||
"type": "compact_20260112"
|
||||
}
|
||||
]
|
||||
},
|
||||
"max_tokens": 100
|
||||
}'
|
||||
```
|
||||
|
||||
**Streaming Support**
|
||||
|
||||
Compaction blocks are also supported in streaming mode. You'll receive:
|
||||
- `compaction_start` event when a compaction block begins
|
||||
- `compaction_delta` events with the compaction content
|
||||
- The accumulated `compaction_blocks` in `provider_specific_fields`
|
||||
|
||||
### Adaptive Thinking
|
||||
|
||||
:::note
|
||||
When using `reasoning_effort` with Claude Opus 4.6, all values (`low`, `medium`, `high`) are mapped to `thinking: {type: "adaptive"}`. To use explicit thinking budgets with `type: "enabled"`, pass the native `thinking` parameter directly (see "Native thinking param" tab below).
|
||||
:::
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="completions" label="/chat/completions">
|
||||
|
||||
LiteLLM supports adaptive thinking through the `reasoning_effort` parameter:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Solve this complex problem: What is the optimal strategy for..."
|
||||
}
|
||||
],
|
||||
"reasoning_effort": "high"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="messages" label="/v1/messages">
|
||||
|
||||
Use the `thinking` parameter with `type: "adaptive"` to enable adaptive thinking mode:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'x-api-key: sk-12345' \
|
||||
--header 'content-type: application/json' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"max_tokens": 16000,
|
||||
"thinking": {
|
||||
"type": "adaptive"
|
||||
},
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Explain why the sum of two even numbers is always even."
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="native" label="Native thinking param">
|
||||
|
||||
Use the `thinking` parameter directly for adaptive thinking via the SDK:
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-opus-4-6",
|
||||
messages=[{"role": "user", "content": "Solve this complex problem: What is the optimal strategy for..."}],
|
||||
thinking={"type": "adaptive"},
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Effort Levels
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="completions" label="/chat/completions">
|
||||
|
||||
Four effort levels available: `low`, `medium`, `high` (default), and `max`. Pass directly via the `output_config` parameter:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Explain quantum computing"
|
||||
}
|
||||
],
|
||||
"output_config": {
|
||||
"effort": "medium"
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
You can use reasoning effort plus output_config to have more control on the model.
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="messages" label="/v1/messages">
|
||||
|
||||
Four effort levels available: `low`, `medium`, `high` (default), and `max`. Pass directly via the `output_config` parameter:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'x-api-key: sk-12345' \
|
||||
--header 'content-type: application/json' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"max_tokens": 4096,
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Explain quantum computing"
|
||||
}
|
||||
],
|
||||
"output_config": {
|
||||
"effort": "medium"
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### 1M Token Context (Beta)
|
||||
|
||||
Opus 4.6 supports 1M token context. Premium pricing applies for prompts exceeding 200k tokens ($10/$37.50 per million input/output tokens). LiteLLM supports cost calculations for 1M token contexts.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="completions" label="/chat/completions">
|
||||
|
||||
To use the 1M token context window, you need to forward the `anthropic-beta` header from your client to the LLM provider.
|
||||
|
||||
**Step 1: Enable header forwarding in your config**
|
||||
|
||||
```yaml
|
||||
general_settings:
|
||||
forward_client_headers_to_llm_api: true
|
||||
```
|
||||
|
||||
**Step 2: Send requests with the beta header**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--header 'anthropic-beta: context-1m-2025-08-07' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Analyze this large document..."
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="messages" label="/v1/messages">
|
||||
|
||||
To use the 1M token context window, you need to forward the `anthropic-beta` header from your client to the LLM provider.
|
||||
|
||||
**Step 1: Enable header forwarding in your config**
|
||||
|
||||
```yaml
|
||||
general_settings:
|
||||
forward_client_headers_to_llm_api: true
|
||||
```
|
||||
|
||||
**Step 2: Send requests with the beta header**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'x-api-key: sk-12345' \
|
||||
--header 'anthropic-beta: context-1m-2025-08-07' \
|
||||
--header 'content-type: application/json' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"max_tokens": 16000,
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Analyze this large document..."
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
:::tip
|
||||
You can combine multiple beta headers by separating them with commas:
|
||||
```bash
|
||||
--header 'anthropic-beta: context-1m-2025-08-07,compact-2026-01-12'
|
||||
```
|
||||
:::
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### US-Only Inference
|
||||
|
||||
Available at 1.1× token pricing. LiteLLM automatically tracks costs for US-only inference.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="completions" label="/chat/completions">
|
||||
|
||||
Use the `inference_geo` parameter to specify US-only inference:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What is the capital of France?"
|
||||
}
|
||||
],
|
||||
"inference_geo": "us"
|
||||
}'
|
||||
```
|
||||
|
||||
LiteLLM will automatically apply the 1.1× pricing multiplier for US-only inference in cost tracking.
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="messages" label="/v1/messages">
|
||||
|
||||
Use the `inference_geo` parameter to specify US-only inference:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'x-api-key: sk-12345' \
|
||||
--header 'content-type: application/json' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"max_tokens": 4096,
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What is the capital of France?"
|
||||
}
|
||||
],
|
||||
"inference_geo": "us"
|
||||
}'
|
||||
```
|
||||
|
||||
LiteLLM will automatically apply the 1.1× pricing multiplier for US-only inference in cost tracking.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Fast Mode
|
||||
|
||||
:::info
|
||||
Fast mode is **only supported on the Anthropic provider** (`anthropic/claude-opus-4-6`). It is not available on Azure AI, Vertex AI, or Bedrock.
|
||||
:::
|
||||
|
||||
**Pricing:**
|
||||
- Standard: $5 input / $25 output per MTok
|
||||
- Fast: $30 input / $150 output per MTok (6× premium)
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="completions" label="/chat/completions">
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Refactor this module..."
|
||||
}
|
||||
],
|
||||
"max_tokens": 4096,
|
||||
"speed": "fast"
|
||||
}'
|
||||
```
|
||||
|
||||
**Using OpenAI SDK:**
|
||||
|
||||
```python
|
||||
import openai
|
||||
|
||||
client = openai.OpenAI(
|
||||
api_key="your-litellm-key",
|
||||
base_url="http://0.0.0.0:4000"
|
||||
)
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="claude-opus-4-6",
|
||||
messages=[{"role": "user", "content": "Refactor this module..."}],
|
||||
max_tokens=4096,
|
||||
extra_body={"speed": "fast"}
|
||||
)
|
||||
```
|
||||
|
||||
**Using LiteLLM SDK:**
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="anthropic/claude-opus-4-6",
|
||||
messages=[{"role": "user", "content": "Refactor this module..."}],
|
||||
max_tokens=4096,
|
||||
speed="fast"
|
||||
)
|
||||
```
|
||||
|
||||
LiteLLM automatically tracks the higher costs for fast mode in usage and cost calculations.
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="messages" label="/v1/messages">
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'x-api-key: sk-12345' \
|
||||
--header 'content-type: application/json' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"max_tokens": 4096,
|
||||
"speed": "fast",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Refactor this module..."
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
LiteLLM automatically:
|
||||
- Adds the `fast-mode-2026-02-01` beta header
|
||||
- Tracks the 6× premium pricing in cost calculations
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
220
docs/my-website/blog/fastapi_middleware_performance/index.mdx
Normal file
|
|
@ -0,0 +1,220 @@
|
|||
---
|
||||
slug: fastapi-middleware-performance
|
||||
title: "Your Middleware Could Be a Bottleneck"
|
||||
date: 2026-02-07T10:00:00
|
||||
authors:
|
||||
- name: Krrish Dholakia
|
||||
title: "CEO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
- name: Ryan Crabbe
|
||||
title: "Performance Engineer, LiteLLM"
|
||||
url: https://www.linkedin.com/in/ryan-crabbe-0b9687214
|
||||
image_url: https://media.licdn.com/dms/image/v2/D5603AQHt1t9Z4BJ6Gw/profile-displayphoto-shrink_400_400/profile-displayphoto-shrink_400_400/0/1724453682340?e=1772064000&v=beta&t=VXdmr13rsNB05wyA2F1TENOB5UuDHUZ0FCHTolNyR5M
|
||||
description: "How we improved LiteLLM proxy latency and throughput by replacing a single middleware base class"
|
||||
tags: [performance, fastapi, middleware]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import { BaseHTTPMiddlewareAnimation, PureASGIAnimation, BenchmarkVisualization } from '@site/src/components/MiddlewareDiagrams';
|
||||
|
||||
> How we improved LiteLLM proxy latency and throughput by replacing a single, simple middleware base class
|
||||
|
||||
---
|
||||
|
||||
## Our Setup
|
||||
|
||||
The LiteLLM proxy server has two middleware layers. The first is Starlette's `CORSMiddleware` (re-exported by FastAPI), which is a pure ASGI middleware. Then we have a simple BaseHTTPMiddleware called PrometheusAuthMiddleware.
|
||||
|
||||
The job of `PrometheusAuthMiddleware` is to authenticate requests to the `/metrics` endpoint. It's not on by default, you enable it with a flag in your proxy config:
|
||||
|
||||
<details>
|
||||
<summary>Proxy config flag</summary>
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
require_auth_for_metrics_endpoint: true
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
The middleware checks two things: is the request hitting `/metrics`, and is auth even enabled? If both checks fail, which they do for the vast majority of requests, it just passes the request through unchanged.
|
||||
|
||||
<details>
|
||||
<summary>PrometheusAuthMiddleware source</summary>
|
||||
|
||||
```python
|
||||
class PrometheusAuthMiddleware(BaseHTTPMiddleware):
|
||||
async def dispatch(self, request: Request, call_next):
|
||||
if self._is_prometheus_metrics_endpoint(request):
|
||||
if self._should_run_auth_on_metrics_endpoint() is True:
|
||||
try:
|
||||
await user_api_key_auth(request=request, api_key=...)
|
||||
except Exception as e:
|
||||
return JSONResponse(status_code=401, content=...)
|
||||
response = await call_next(request)
|
||||
return response
|
||||
|
||||
@staticmethod
|
||||
def _is_prometheus_metrics_endpoint(request: Request):
|
||||
if "/metrics" in request.url.path:
|
||||
return True
|
||||
return False
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
Looks harmless. Subclass `BaseHTTPMiddleware`, implement `dispatch()`, done. This is what you will see in Starlette's documentation<sup>[1](#footnote-1)</sup>.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
---
|
||||
|
||||
## What BaseHTTPMiddleware Actually Does
|
||||
|
||||
When you write a `dispatch()` method, you'd expect the request to flow straight through your function and out the other side. What actually happens is much more involved.
|
||||
|
||||
On every request, even a pure passthrough (meaning nothing happens), `BaseHTTPMiddleware` creates **7 intermediate objects and tasks**:
|
||||
|
||||
<BaseHTTPMiddlewareAnimation />
|
||||
|
||||
It wraps the request in a new object to track body state, creates a synchronization event, allocates an in-memory channel to pass messages between your middleware and the inner app, sets up a task group to manage the lifecycle, and then runs your actual route handler in a *separate background task* when you call `call_next()`. The response body then flows back through that in-memory channel, gets re-wrapped in a streaming response object, and finally reaches the caller. That's a lot.
|
||||
|
||||
For a middleware that for us, does nothing on 99.9% of requests, paying this cost doesn't make sense.
|
||||
|
||||
Compare that to a pure ASGI middleware, which we can have just check the request path and continue along.
|
||||
|
||||
<PureASGIAnimation />
|
||||
|
||||
Our middleware is doing something really simple. For the vast majority of requests it doesn't need to do anything at all but just let the request pass through. It doesn't need task groups, memory streams, or cancel scopes. It needs a function call.
|
||||
|
||||
---
|
||||
|
||||
## Comparing Both
|
||||
|
||||
We replaced the `BaseHTTPMiddleware` subclass with a pure ASGI middleware. To benchmark the difference, we used Apache Bench<sup>[2](#footnote-2)</sup> to compare both configurations of LiteLLM's middleware stack: the old setup (1 pure ASGI + 1 `BaseHTTPMiddleware`) against the new setup (2 pure ASGI).
|
||||
|
||||
A minimal FastAPI app serves `GET /health` → `PlainTextResponse("ok")`. The endpoint does zero work to isolate the middleware overhead: any difference between configs is purely the cost of the middleware plumbing itself. Both middlewares are just calling the next layer. Same work, different base class.
|
||||
|
||||
Apache Bench (`ab`) fires requests at the server with 1,000 concurrent connections and a single uvicorn worker. One worker means one event loop, so the benchmark directly measures how each middleware design handles concurrent load on a single thread.
|
||||
|
||||
<BenchmarkVisualization />
|
||||
|
||||
<details>
|
||||
<summary>Try it yourself</summary>
|
||||
|
||||
Save the script below as `benchmark_middleware.py`, then run:
|
||||
|
||||
```bash
|
||||
# Terminal 1 — start the "before" server (1 ASGI + 1 BaseHTTPMiddleware)
|
||||
python benchmark_middleware.py --middleware mixed
|
||||
|
||||
# Terminal 2 — benchmark it
|
||||
ab -n 50000 -c 1000 http://localhost:8000/health
|
||||
|
||||
# Stop the server, then start the "after" server (2x pure ASGI)
|
||||
python benchmark_middleware.py --middleware asgi
|
||||
|
||||
# Terminal 2 — benchmark again
|
||||
ab -n 50000 -c 1000 http://localhost:8000/health
|
||||
```
|
||||
|
||||
```python
|
||||
import argparse
|
||||
import uvicorn
|
||||
from fastapi import FastAPI
|
||||
from fastapi.responses import PlainTextResponse
|
||||
from starlette.middleware.base import BaseHTTPMiddleware
|
||||
from starlette.requests import Request
|
||||
from starlette.types import ASGIApp, Receive, Scope, Send
|
||||
|
||||
|
||||
class NoOpBaseHTTPMiddleware(BaseHTTPMiddleware):
|
||||
async def dispatch(self, request: Request, call_next):
|
||||
return await call_next(request)
|
||||
|
||||
|
||||
class NoOpPureASGIMiddleware:
|
||||
def __init__(self, app: ASGIApp) -> None:
|
||||
self.app = app
|
||||
|
||||
async def __call__(self, scope: Scope, receive: Receive, send: Send) -> None:
|
||||
await self.app(scope, receive, send)
|
||||
|
||||
|
||||
def create_app(middleware_type: str | None = None, layers: int = 2) -> FastAPI:
|
||||
app = FastAPI()
|
||||
|
||||
@app.get("/health")
|
||||
async def health():
|
||||
return PlainTextResponse("ok")
|
||||
|
||||
if middleware_type == "mixed":
|
||||
app.add_middleware(NoOpBaseHTTPMiddleware)
|
||||
app.add_middleware(NoOpPureASGIMiddleware)
|
||||
elif middleware_type == "asgi":
|
||||
for _ in range(layers):
|
||||
app.add_middleware(NoOpPureASGIMiddleware)
|
||||
|
||||
return app
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--middleware", choices=["asgi", "mixed"], default=None)
|
||||
parser.add_argument("--layers", type=int, default=2)
|
||||
parser.add_argument("--port", type=int, default=8000)
|
||||
args = parser.parse_args()
|
||||
|
||||
app = create_app(middleware_type=args.middleware, layers=args.layers)
|
||||
uvicorn.run(app, host="0.0.0.0", port=args.port, workers=1, log_level="warning")
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## Our Change
|
||||
|
||||
Here's what we replaced it with:
|
||||
|
||||
```python
|
||||
class PrometheusAuthMiddleware:
|
||||
def __init__(self, app: ASGIApp) -> None:
|
||||
self.app = app
|
||||
|
||||
async def __call__(self, scope: Scope, receive: Receive, send: Send) -> None:
|
||||
if scope["type"] != "http" or "/metrics" not in scope.get("path", ""):
|
||||
await self.app(scope, receive, send)
|
||||
return
|
||||
|
||||
if litellm.require_auth_for_metrics_endpoint is True:
|
||||
request = Request(scope, receive)
|
||||
api_key = request.headers.get("Authorization") or ""
|
||||
try:
|
||||
await user_api_key_auth(request=request, api_key=api_key)
|
||||
except Exception as e:
|
||||
# send 401 directly via ASGI protocol
|
||||
...
|
||||
return
|
||||
|
||||
await self.app(scope, receive, send)
|
||||
```
|
||||
|
||||
For the 99.9% of requests that aren't hitting `/metrics`, the middleware is now one dict lookup, one string check, and one function call. No objects allocated, no tasks spawned.
|
||||
|
||||
It's important to evaluate if the tools you're using are the right fit for the job as your software grows and handles more responsiblity. We're now putting in a static analysis check to prevent this from happening again with any newly introduced middlewares. If we find the use case is necessary then that's okay and we'll reevalute but for everything LiteLLM needs to do at the moment it's not.
|
||||
|
||||
This middleware change was one part of a broader optimization effort on the LiteLLM proxy. Across all optimizations combined, we've measured about a **30% reduction in proxy overhead** over the past two weeks.
|
||||
|
||||
---
|
||||
|
||||
<a id="footnote-1"></a>
|
||||
<sup>1</sup> [Starlette Middleware — BaseHTTPMiddleware](https://starlette.dev/middleware/#basehttpmiddleware)
|
||||
|
||||
<a id="footnote-2"></a>
|
||||
<sup>2</sup> [Apache HTTP server benchmarking tool (`ab`)](https://httpd.apache.org/docs/2.4/programs/ab.html)
|
||||
136
docs/my-website/blog/litellm_observatory/index.md
Normal file
|
|
@ -0,0 +1,136 @@
|
|||
---
|
||||
slug: litellm-observatory
|
||||
title: "Improve release stability with 24 hour load tests"
|
||||
date: 2026-02-06T10:00:00
|
||||
authors:
|
||||
- name: Alexsander Hamir
|
||||
title: "Performance Engineer, LiteLLM"
|
||||
url: https://www.linkedin.com/in/alexsander-baptista/
|
||||
image_url: https://github.com/AlexsanderHamir.png
|
||||
- name: Krrish Dholakia
|
||||
title: "CEO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
description: "How we built a long-running, release-validation system to catch regressions before they reach users."
|
||||
tags: [testing, observability, reliability, releases]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
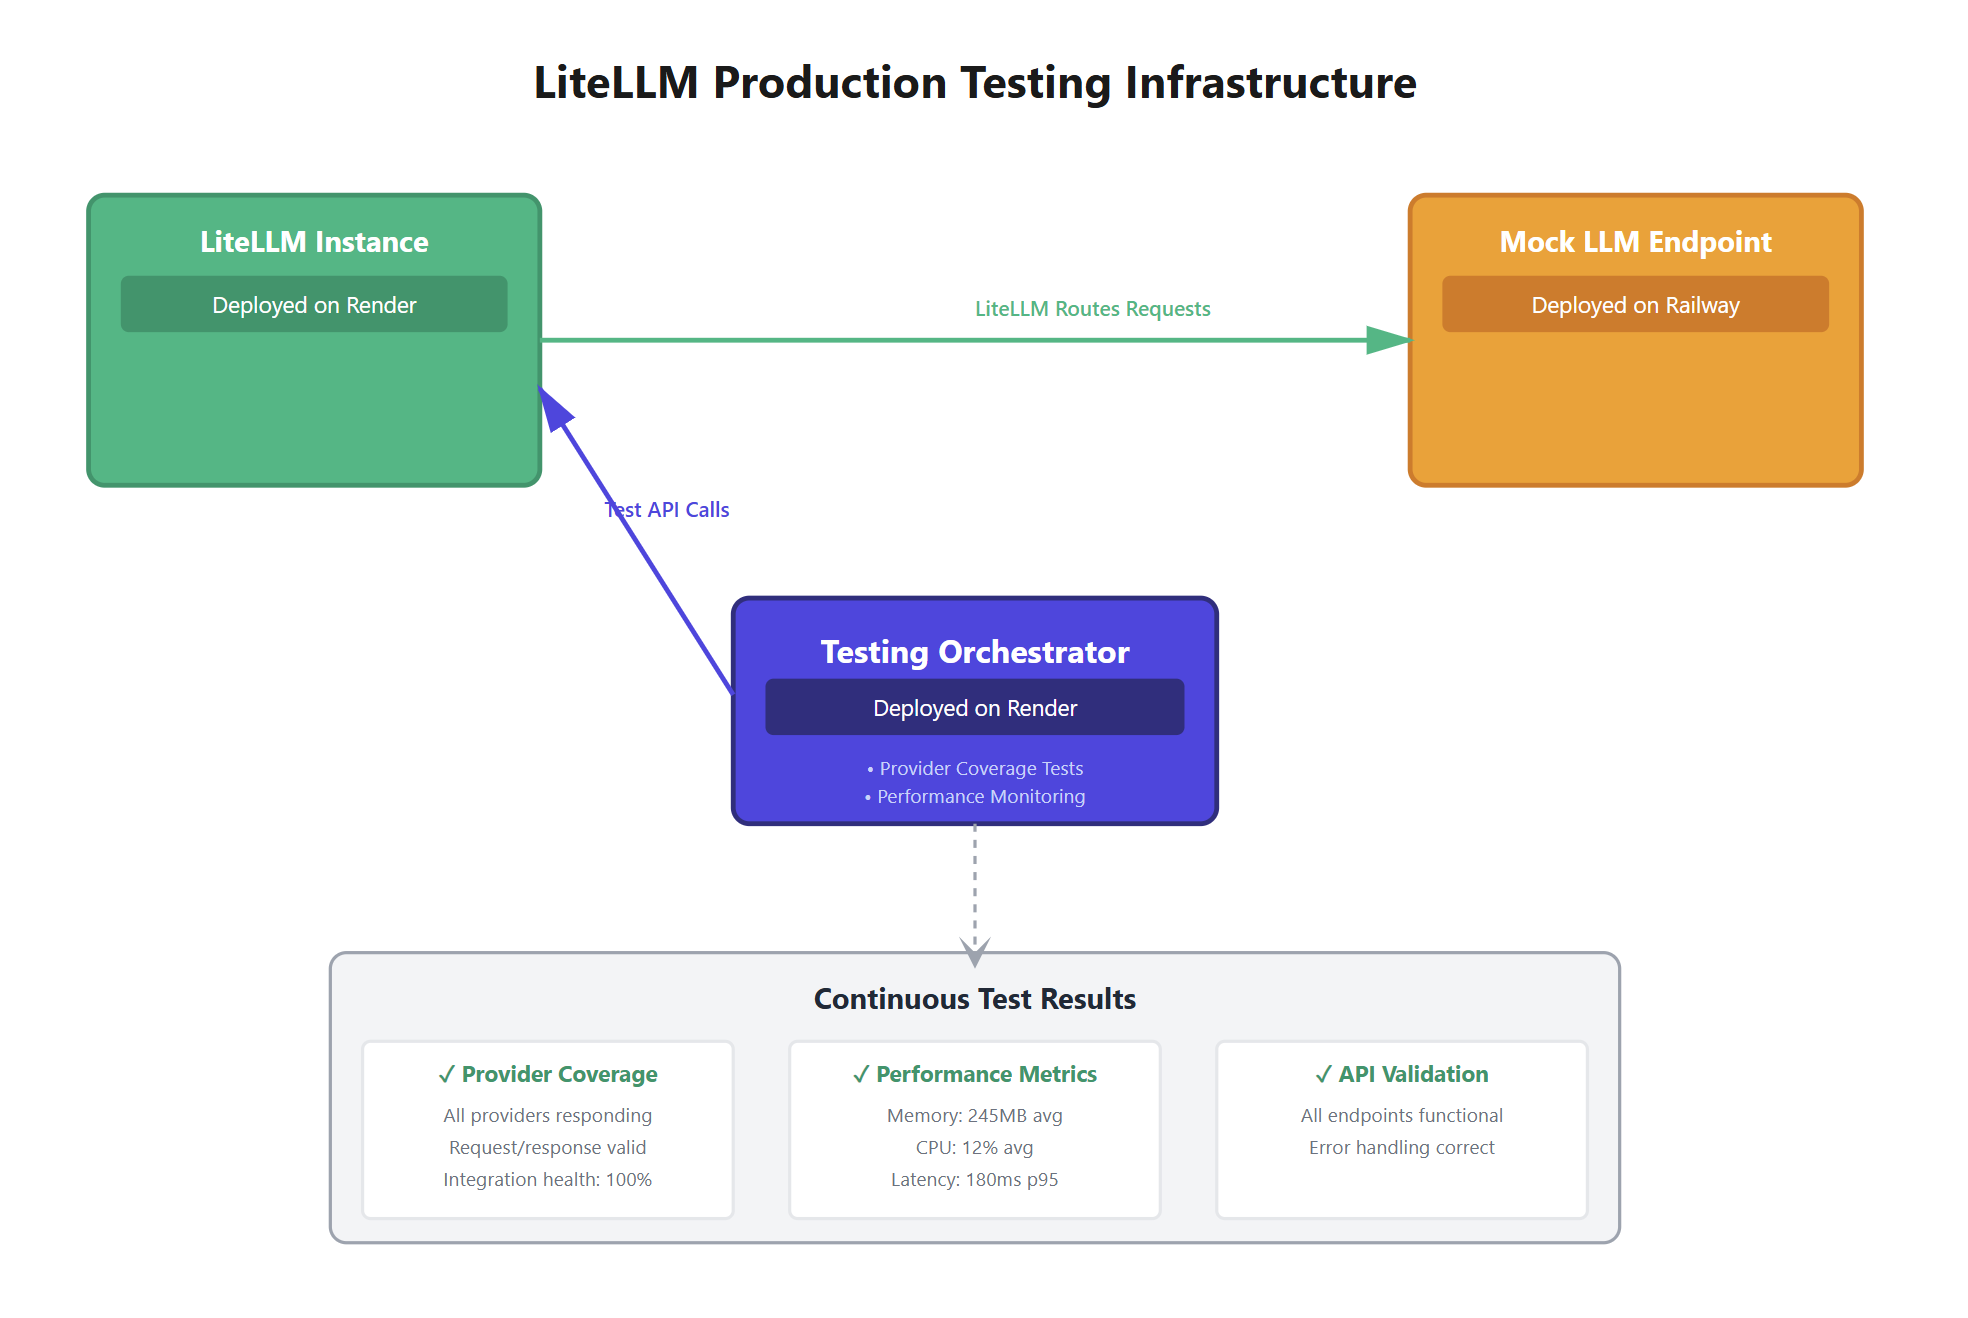
|
||||
|
||||
# Improve release stability with 24 hour load tests
|
||||
|
||||
As LiteLLM adoption has grown, so have expectations around reliability, performance, and operational safety. Meeting those expectations requires more than correctness-focused tests, it requires validating how the system behaves over time, under real-world conditions.
|
||||
|
||||
This post introduces **LiteLLM Observatory**, a long-running release-validation system we built to catch regressions before they reach users.
|
||||
|
||||
---
|
||||
|
||||
## Why We Built the Observatory
|
||||
|
||||
LiteLLM operates at the intersection of external providers, long-lived network connections, and high-throughput workloads. While our unit and integration tests do an excellent job validating correctness, they are not designed to surface issues that only appear after extended operation.
|
||||
|
||||
A subtle lifecycle edge case discovered in v1.81.3 reinforced the need for stronger release validation in this area.
|
||||
|
||||
---
|
||||
|
||||
## A Real-World Lifecycle Edge Case
|
||||
|
||||
In v1.81.3, we shipped a fix for an HTTP client memory leak. The change passed unit and integration tests and behaved correctly in short-lived runs.
|
||||
|
||||
The issue that surfaced was not caused by a single incorrect line of logic, but by how multiple components interacted over time:
|
||||
|
||||
- A cached `httpx` client was configured with a 1-hour TTL
|
||||
- When the cache expired, the underlying HTTP connection was closed as expected
|
||||
- A higher-level client continued to hold a reference to that connection
|
||||
- Subsequent requests failed with:
|
||||
|
||||
```
|
||||
Cannot send a request, as the client has been closed
|
||||
```
|
||||
|
||||
**Before (with bug):**
|
||||
|
||||
| Provider | Requests | Success | Failures | Fail % |
|
||||
|----------|----------|---------|----------|--------|
|
||||
| OpenAI | 720,000 | 432,000 | 288,000 | 40% |
|
||||
| Azure | 692,000 | 415,200 | 276,800 | 40% |
|
||||
|
||||
**After (fixed):**
|
||||
|
||||
| Provider | Requests | Success | Failures | Fail % |
|
||||
|----------|------------|-----------|----------|---------|
|
||||
| OpenAI | 1,200,000 | 1,199,988 | 12 | 0.001% |
|
||||
| Azure | 1,150,000 | 1,149,982 | 18 | 0.002% |
|
||||
|
||||
Our focus moving forward is on being the first to detect issues, even when they aren’t covered by unit tests. LiteLLM Observatory is designed to surface latency regressions, OOMs, and failure modes that only appear under real traffic patterns in **our own production deployments** during release validation.
|
||||
|
||||
|
||||
---
|
||||
|
||||
### How the Observatory Works
|
||||
|
||||
[LiteLLM Observatory](https://github.com/BerriAI/litellm-observatory) is a testing service that runs long-running tests against our LiteLLM deployments. We trigger tests by sending API requests, and results are automatically sent to Slack when tests complete.
|
||||
|
||||
#### How Tests Run
|
||||
|
||||
1. **Start a Test**: We send a request to the Observatory API with:
|
||||
- Which LiteLLM deployment to test (URL and API key)
|
||||
- Which test to run (e.g., `TestOAIAzureRelease`)
|
||||
- Test settings (which models to test, how long to run, failure thresholds)
|
||||
|
||||
2. **Smart Queueing**:
|
||||
- The system checks whether we are attempting to run the exact same test more than once
|
||||
- If a duplicate test is already running or queued, we receive an error to avoid wasting resources
|
||||
- Otherwise, the test is added to a queue and runs when capacity is available (up to 5 tests can run concurrently by default)
|
||||
|
||||
3. **Instant Response**: The API responds immediately—we do not wait for the test to finish. Tests may run for hours, but the request itself completes in milliseconds.
|
||||
|
||||
4. **Background Execution**:
|
||||
- The test runs in the background, issuing requests against our LiteLLM deployment
|
||||
- It tracks request success and failure rates over time
|
||||
- When the test completes, results are automatically posted to our Slack channel
|
||||
|
||||
#### Example: The OpenAI / Azure Reliability Test
|
||||
|
||||
The `TestOAIAzureRelease` test is designed to catch a class of bugs that only surface after sustained runtime:
|
||||
|
||||
- **Duration**: Runs continuously for 3 hours
|
||||
- **Behavior**: Cycles through specified models (such as `gpt-4` and `gpt-3.5-turbo`), issuing requests continuously
|
||||
- **Why 3 Hours**: This helps catch issues where HTTP clients degrade or fail after extended use (for example, a bug observed in LiteLLM v1.81.3)
|
||||
- **Pass / Fail Criteria**: The test passes if fewer than 1% of requests fail. If the failure rate exceeds 1%, the test fails and we are notified in Slack
|
||||
- **Key Detail**: The same HTTP client is reused for the entire run, allowing us to detect lifecycle-related bugs that only appear under prolonged reuse
|
||||
|
||||
#### When We Use It
|
||||
|
||||
- **Before Deployments**: Run tests before promoting a new LiteLLM version to production
|
||||
- **Routine Validation**: Schedule regular runs (daily or weekly) to catch regressions early
|
||||
- **Issue Investigation**: Run tests on demand when we suspect a deployment issue
|
||||
- **Long-Running Failure Detection**: Identify bugs that only appear under sustained load, beyond what short smoke tests can reveal
|
||||
|
||||
|
||||
### Complementing Unit Tests
|
||||
|
||||
Unit tests remain a foundational part of our development process. They are fast and precise, but they don’t cover:
|
||||
|
||||
- Real provider behavior
|
||||
- Long-lived network interactions
|
||||
- Resource lifecycle edge cases
|
||||
- Time-dependent regressions
|
||||
|
||||
LiteLLM Observatory complements unit tests by validating the system as it actually runs in production-like environments.
|
||||
|
||||
---
|
||||
|
||||
### Looking Ahead
|
||||
|
||||
Reliability is an ongoing investment.
|
||||
|
||||
LiteLLM Observatory is one of several systems we’re building to continuously raise the bar on release quality and operational safety. As LiteLLM evolves, so will our validation tooling, informed by real-world usage and lessons learned.
|
||||
|
||||
We’ll continue to share those improvements openly as we go.
|
||||
|
||||
394
docs/my-website/blog/minimax_m2_5/index.md
Normal file
|
|
@ -0,0 +1,394 @@
|
|||
---
|
||||
slug: minimax_m2_5
|
||||
title: "Day 0 Support: MiniMax-M2.5"
|
||||
date: 2026-02-12T10:00:00
|
||||
authors:
|
||||
- name: Sameer Kankute
|
||||
title: SWE @ LiteLLM (LLM Translation)
|
||||
url: https://www.linkedin.com/in/sameer-kankute/
|
||||
image_url: https://pbs.twimg.com/profile_images/2001352686994907136/ONgNuSk5_400x400.jpg
|
||||
- name: Krrish Dholakia
|
||||
title: "CEO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
description: "Day 0 support for MiniMax-M2.5 on LiteLLM"
|
||||
tags: [minimax, M2.5, llm]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
LiteLLM now supports MiniMax-M2.5 on Day 0. Use it across OpenAI-compatible and Anthropic-compatible APIs through the LiteLLM AI Gateway.
|
||||
|
||||
## Supported Models
|
||||
|
||||
LiteLLM supports the following MiniMax models:
|
||||
|
||||
| Model | Description | Input Cost | Output Cost | Context Window |
|
||||
|-------|-------------|------------|-------------|----------------|
|
||||
| **MiniMax-M2.5** | Advanced reasoning, Agentic capabilities | $0.3/M tokens | $1.2/M tokens | 1M tokens |
|
||||
| **MiniMax-M2.5-lightning** | Faster and More Agile (~100 tps) | $0.3/M tokens | $2.4/M tokens | 1M tokens |
|
||||
|
||||
## Features Supported
|
||||
|
||||
- **Prompt Caching**: Reduce costs with cached prompts ($0.03/M tokens for cache read, $0.375/M tokens for cache write)
|
||||
- **Function Calling**: Built-in tool calling support
|
||||
- **Reasoning**: Advanced reasoning capabilities with thinking support
|
||||
- **System Messages**: Full system message support
|
||||
- **Cost Tracking**: Automatic cost calculation for all requests
|
||||
|
||||
## Docker Image
|
||||
|
||||
```bash
|
||||
docker pull litellm/litellm:v1.81.3-stable
|
||||
```
|
||||
|
||||
## Usage - OpenAI Compatible API (/v1/chat/completions)
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: minimax-m2-5
|
||||
litellm_params:
|
||||
model: minimax/MiniMax-M2.5
|
||||
api_key: os.environ/MINIMAX_API_KEY
|
||||
api_base: https://api.minimax.io/v1
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e MINIMAX_API_KEY=$MINIMAX_API_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:v1.81.3-stable \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "minimax-m2-5",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### With Reasoning Split
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "minimax-m2-5",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Solve: 2+2=?"
|
||||
}
|
||||
],
|
||||
"extra_body": {
|
||||
"reasoning_split": true
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
## Usage - Anthropic Compatible API (/v1/messages)
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: minimax-m2-5
|
||||
litellm_params:
|
||||
model: minimax/MiniMax-M2.5
|
||||
api_key: os.environ/MINIMAX_API_KEY
|
||||
api_base: https://api.minimax.io/anthropic/v1/messages
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e MINIMAX_API_KEY=$MINIMAX_API_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:v1.81.3-stable \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "minimax-m2-5",
|
||||
"max_tokens": 1000,
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### With Thinking
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "minimax-m2-5",
|
||||
"max_tokens": 1000,
|
||||
"thinking": {
|
||||
"type": "enabled",
|
||||
"budget_tokens": 1000
|
||||
},
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Solve: 2+2=?"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
## Usage - LiteLLM SDK
|
||||
|
||||
### OpenAI-compatible API
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[
|
||||
{"role": "user", "content": "Hello, how are you?"}
|
||||
],
|
||||
api_key="your-minimax-api-key",
|
||||
api_base="https://api.minimax.io/v1"
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
### Anthropic-compatible API
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.anthropic.messages.acreate(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[{"role": "user", "content": "Hello, how are you?"}],
|
||||
api_key="your-minimax-api-key",
|
||||
api_base="https://api.minimax.io/anthropic/v1/messages",
|
||||
max_tokens=1000
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
### With Thinking
|
||||
|
||||
```python
|
||||
response = litellm.anthropic.messages.acreate(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[{"role": "user", "content": "Solve: 2+2=?"}],
|
||||
thinking={"type": "enabled", "budget_tokens": 1000},
|
||||
api_key="your-minimax-api-key"
|
||||
)
|
||||
|
||||
# Access thinking content
|
||||
for block in response.choices[0].message.content:
|
||||
if hasattr(block, 'type') and block.type == 'thinking':
|
||||
print(f"Thinking: {block.thinking}")
|
||||
```
|
||||
|
||||
### With Reasoning Split (OpenAI API)
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[
|
||||
{"role": "user", "content": "Solve: 2+2=?"}
|
||||
],
|
||||
extra_body={"reasoning_split": True},
|
||||
api_key="your-minimax-api-key",
|
||||
api_base="https://api.minimax.io/v1"
|
||||
)
|
||||
|
||||
# Access thinking and response
|
||||
if hasattr(response.choices[0].message, 'reasoning_details'):
|
||||
print(f"Thinking: {response.choices[0].message.reasoning_details}")
|
||||
print(f"Response: {response.choices[0].message.content}")
|
||||
```
|
||||
|
||||
## Cost Tracking
|
||||
|
||||
LiteLLM automatically tracks costs for MiniMax-M2.5 requests. The pricing is:
|
||||
|
||||
- **Input**: $0.3 per 1M tokens
|
||||
- **Output**: $1.2 per 1M tokens
|
||||
- **Cache Read**: $0.03 per 1M tokens
|
||||
- **Cache Write**: $0.375 per 1M tokens
|
||||
|
||||
### Accessing Cost Information
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[{"role": "user", "content": "Hello!"}],
|
||||
api_key="your-minimax-api-key"
|
||||
)
|
||||
|
||||
# Access cost information
|
||||
print(f"Cost: ${response._hidden_params.get('response_cost', 0)}")
|
||||
```
|
||||
|
||||
## Streaming Support
|
||||
|
||||
### OpenAI API
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[{"role": "user", "content": "Tell me a story"}],
|
||||
stream=True,
|
||||
api_key="your-minimax-api-key",
|
||||
api_base="https://api.minimax.io/v1"
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
if chunk.choices[0].delta.content:
|
||||
print(chunk.choices[0].delta.content, end="")
|
||||
```
|
||||
|
||||
### Streaming with Reasoning Split
|
||||
|
||||
```python
|
||||
stream = litellm.completion(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[
|
||||
{"role": "user", "content": "Tell me a story"},
|
||||
],
|
||||
extra_body={"reasoning_split": True},
|
||||
stream=True,
|
||||
api_key="your-minimax-api-key",
|
||||
api_base="https://api.minimax.io/v1"
|
||||
)
|
||||
|
||||
reasoning_buffer = ""
|
||||
text_buffer = ""
|
||||
|
||||
for chunk in stream:
|
||||
if hasattr(chunk.choices[0].delta, "reasoning_details") and chunk.choices[0].delta.reasoning_details:
|
||||
for detail in chunk.choices[0].delta.reasoning_details:
|
||||
if "text" in detail:
|
||||
reasoning_text = detail["text"]
|
||||
new_reasoning = reasoning_text[len(reasoning_buffer):]
|
||||
if new_reasoning:
|
||||
print(new_reasoning, end="", flush=True)
|
||||
reasoning_buffer = reasoning_text
|
||||
|
||||
if chunk.choices[0].delta.content:
|
||||
content_text = chunk.choices[0].delta.content
|
||||
new_text = content_text[len(text_buffer):] if text_buffer else content_text
|
||||
if new_text:
|
||||
print(new_text, end="", flush=True)
|
||||
text_buffer = content_text
|
||||
```
|
||||
|
||||
## Using with Native SDKs
|
||||
|
||||
### Anthropic SDK via LiteLLM Proxy
|
||||
|
||||
```python
|
||||
import os
|
||||
os.environ["ANTHROPIC_BASE_URL"] = "http://localhost:4000"
|
||||
os.environ["ANTHROPIC_API_KEY"] = "sk-1234" # Your LiteLLM proxy key
|
||||
|
||||
import anthropic
|
||||
|
||||
client = anthropic.Anthropic()
|
||||
|
||||
message = client.messages.create(
|
||||
model="minimax-m2-5",
|
||||
max_tokens=1000,
|
||||
system="You are a helpful assistant.",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "text",
|
||||
"text": "Hi, how are you?"
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
)
|
||||
|
||||
for block in message.content:
|
||||
if block.type == "thinking":
|
||||
print(f"Thinking:\n{block.thinking}\n")
|
||||
elif block.type == "text":
|
||||
print(f"Text:\n{block.text}\n")
|
||||
```
|
||||
|
||||
### OpenAI SDK via LiteLLM Proxy
|
||||
|
||||
```python
|
||||
import os
|
||||
os.environ["OPENAI_BASE_URL"] = "http://localhost:4000"
|
||||
os.environ["OPENAI_API_KEY"] = "sk-1234" # Your LiteLLM proxy key
|
||||
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI()
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="minimax-m2-5",
|
||||
messages=[
|
||||
{"role": "system", "content": "You are a helpful assistant."},
|
||||
{"role": "user", "content": "Hi, how are you?"},
|
||||
],
|
||||
extra_body={"reasoning_split": True},
|
||||
)
|
||||
|
||||
# Access thinking and response
|
||||
if hasattr(response.choices[0].message, 'reasoning_details'):
|
||||
print(f"Thinking:\n{response.choices[0].message.reasoning_details[0]['text']}\n")
|
||||
print(f"Text:\n{response.choices[0].message.content}\n")
|
||||
```
|
||||
95
docs/my-website/blog/model_cost_map_incident/index.md
Normal file
|
|
@ -0,0 +1,95 @@
|
|||
---
|
||||
slug: model-cost-map-incident
|
||||
title: "Incident Report: Invalid model cost map on main"
|
||||
date: 2026-02-10T10:00:00
|
||||
authors:
|
||||
- name: Ishaan Jaffer
|
||||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/ishaanjaffer/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
tags: [incident-report, stability]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
**Date:** January 27, 2026
|
||||
**Duration:** ~20 minutes
|
||||
**Severity:** Low
|
||||
**Status:** Resolved
|
||||
|
||||
## Summary
|
||||
|
||||
A malformed JSON entry in `model_prices_and_context_window.json` was merged to `main` ([`562f0a0`](https://github.com/BerriAI/litellm/commit/562f0a028251750e3d75386bee0e630d9796d0df)). This caused LiteLLM to silently fall back to a stale local copy of the model cost map. Users on older package versions lost cost tracking for newer models only (e.g. `azure/gpt-5.2`). No LLM calls were blocked.
|
||||
|
||||
- **LLM calls and proxy routing:** No impact.
|
||||
- **Cost tracking:** Impacted for newer models not present in the local backup. Older models were unaffected. The incident lasted ~20 minutes until the commit was reverted.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
---
|
||||
|
||||
## Background
|
||||
|
||||
The model cost map is not in the request path. It is used after the LLM response comes back, inside a try/catch, to calculate spend. A missing entry never blocks a call.
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
A["1. litellm.completion() receives request
|
||||
litellm/main.py"] --> B["2. Route to provider
|
||||
litellm/litellm_core_utils/get_llm_provider_logic.py"]
|
||||
B --> C["3. LLM returns response
|
||||
litellm/main.py"]
|
||||
C --> D["4. Post-call: look up model in cost map
|
||||
litellm/cost_calculator.py"]
|
||||
D -->|"found"| E["5a. Attach cost to response"]
|
||||
D -->|"not found (try/catch)"| F["5b. Log warning, set cost=0"]
|
||||
E --> G["6. Return response to caller"]
|
||||
F --> G
|
||||
|
||||
style D fill:#fff3cd,stroke:#ffc107
|
||||
style F fill:#fff3cd,stroke:#ffc107
|
||||
style E fill:#d4edda,stroke:#28a745
|
||||
style G fill:#d4edda,stroke:#28a745
|
||||
```
|
||||
|
||||
Both paths return a response to the caller. When the cost map lookup fails, the only difference is `cost=0` on that request.
|
||||
|
||||
---
|
||||
|
||||
## Root cause
|
||||
|
||||
LiteLLM fetches the model cost map from GitHub `main` at import time. If the fetch fails, it falls back to a local backup bundled with the package. Before this incident, the fallback was completely silent -- no warning was logged.
|
||||
|
||||
A contributor PR introduced an extra `{` bracket, producing invalid JSON. The remote fetch failed with `JSONDecodeError`, triggering the silent fallback. Users on older package versions had backup files missing newer models.
|
||||
|
||||
**Timeline:**
|
||||
|
||||
1. Malformed JSON merged to `main`
|
||||
2. LiteLLM installations fall back to local backup on next import
|
||||
3. Users report `"This model isn't mapped yet"` for newer models
|
||||
4. Bad commit identified and reverted (~20 minutes)
|
||||
|
||||
---
|
||||
|
||||
## Remediation
|
||||
|
||||
| # | Action | Status | Code |
|
||||
|---|---|---|---|
|
||||
| 1 | CI validation on `model_prices_and_context_window.json` | ✅ Done | [`test-model-map.yaml`](https://github.com/BerriAI/litellm/blob/main/.github/workflows/test-model-map.yaml) |
|
||||
| 2 | Warning log on fallback to local backup | ✅ Done | [`get_model_cost_map.py#L57-L68`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm_core_utils/get_model_cost_map.py#L57-L68) |
|
||||
| 3 | `GetModelCostMap` class with integrity validation helpers | ✅ Done | [`get_model_cost_map.py#L24-L149`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm_core_utils/get_model_cost_map.py#L24-L149) |
|
||||
| 4 | Resilience test suite (bad hosted map, fallback, completion) | ✅ Done | [`test_model_cost_map_resilience.py#L150-L291`](https://github.com/BerriAI/litellm/blob/main/tests/llm_translation/test_model_cost_map_resilience.py#L150-L291) |
|
||||
| 5 | Test that backup model cost map always exists and contains common models | ✅ Done | [`test_model_cost_map_resilience.py#L213-L228`](https://github.com/BerriAI/litellm/blob/main/tests/llm_translation/test_model_cost_map_resilience.py#L213-L228) |
|
||||
|
||||
Enterprises that require zero external dependencies at import time can set `LITELLM_LOCAL_MODEL_COST_MAP=True` to skip the GitHub fetch entirely.
|
||||
|
||||
---
|
||||
|
||||
## Other dependencies on external resources
|
||||
|
||||
| Dependency | Impact if unavailable | Fallback |
|
||||
|---|---|---|
|
||||
| Model cost map (GitHub) | Cost tracking for newer models | Local backup (now with warning) |
|
||||
| JWT public keys (IDP/SSO) | Auth fails | None |
|
||||
| OIDC UserInfo (IDP/SSO) | Auth fails | None |
|
||||
| HuggingFace model API | HF provider calls fail | None |
|
||||
| Ollama tags (localhost) | Ollama model list stale | Static list |
|
||||
|
|
@ -93,6 +93,12 @@ Implement `POST /beta/litellm_basic_guardrail_api`
|
|||
"user_api_key_end_user_id": "end user id associated with the litellm virtual key used",
|
||||
"user_api_key_org_id": "org id associated with the litellm virtual key used"
|
||||
},
|
||||
"request_headers": { // optional: inbound request headers (allowlist). Allowed headers show their value; all others show "[present]" to indicate the header existed.
|
||||
"User-Agent": "OpenAI/Python 2.17.0",
|
||||
"Content-Type": "application/json",
|
||||
"X-Request-Id": "[present]"
|
||||
},
|
||||
"litellm_version": "1.x.y", // optional: LiteLLM library version running this proxy
|
||||
"input_type": "request", // "request" or "response"
|
||||
"litellm_call_id": "unique_call_id", // the call id of the individual LLM call
|
||||
"litellm_trace_id": "trace_id", // the trace id of the LLM call - useful if there are multiple LLM calls for the same conversation
|
||||
|
|
|
|||
|
|
@ -101,12 +101,11 @@ model_list:
|
|||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
litellm_settings:
|
||||
guardrails:
|
||||
guardrails:
|
||||
- guardrail_name: my_guardrail
|
||||
litellm_params:
|
||||
litellm_params:
|
||||
guardrail: my_guardrail
|
||||
mode: during_call
|
||||
api_key: os.environ/MY_GUARDRAIL_API_KEY
|
||||
|
|
|
|||
|
|
@ -5,6 +5,13 @@ import Image from '@theme/IdealImage';
|
|||
|
||||
Benchmarks for LiteLLM Gateway (Proxy Server) tested against a fake OpenAI endpoint.
|
||||
|
||||
## Setting Up a Fake OpenAI Endpoint
|
||||
|
||||
For load testing and benchmarking, you can use a fake OpenAI proxy server. LiteLLM provides:
|
||||
|
||||
1. **Hosted endpoint**: Use our free hosted fake endpoint at `https://exampleopenaiendpoint-production.up.railway.app/`
|
||||
2. **Self-hosted**: Set up your own fake OpenAI proxy server using [github.com/BerriAI/example_openai_endpoint](https://github.com/BerriAI/example_openai_endpoint)
|
||||
|
||||
Use this config for testing:
|
||||
|
||||
```yaml
|
||||
|
|
@ -12,7 +19,7 @@ model_list:
|
|||
- model_name: "fake-openai-endpoint"
|
||||
litellm_params:
|
||||
model: openai/any
|
||||
api_base: https://your-fake-openai-endpoint.com/chat/completions
|
||||
api_base: https://exampleopenaiendpoint-production.up.railway.app/ # or your self-hosted endpoint
|
||||
api_key: "test"
|
||||
```
|
||||
|
||||
|
|
|
|||
|
|
@ -18,16 +18,46 @@ Each provider uses their own search backend:
|
|||
|
||||
| Provider | Search Engine | Notes |
|
||||
|----------|---------------|-------|
|
||||
| **OpenAI** (`gpt-4o-search-preview`) | OpenAI's internal search | Real-time web data |
|
||||
| **OpenAI** (`gpt-5-search-api`, `gpt-4o-search-preview`, `gpt-4o-mini-search-preview`) | OpenAI's internal search | Real-time web data |
|
||||
| **xAI** (`grok-3`) | xAI's search + X/Twitter | Real-time social media data |
|
||||
| **Google AI/Vertex** (`gemini-2.0-flash`) | **Google Search** | Uses actual Google search results |
|
||||
| **Anthropic** (`claude-3-5-sonnet`) | Anthropic's web search | Real-time web data |
|
||||
| **Perplexity** | Perplexity's search engine | AI-powered search and reasoning |
|
||||
|
||||
:::warning Important: Only Search Models Support `web_search_options`
|
||||
For OpenAI, only dedicated search models support the `web_search_options` parameter:
|
||||
- `gpt-4o-search-preview`
|
||||
- `gpt-4o-mini-search-preview`
|
||||
- `gpt-5-search-api`
|
||||
|
||||
**Regular models like `gpt-5`, `gpt-4.1`, `gpt-4o` do not support `web_search_options`**
|
||||
:::
|
||||
|
||||
:::tip The `web_search_options` parameter is optional
|
||||
Search models (like `gpt-4o-search-preview`) **automatically search the web** even without the `web_search_options` parameter.
|
||||
|
||||
Use `web_search_options` when you need to:
|
||||
- Adjust `search_context_size` (`"low"`, `"medium"`, `"high"`)
|
||||
- Specify `user_location` for localized results
|
||||
:::
|
||||
|
||||
:::info
|
||||
**Anthropic Web Search Models**: Claude models that support web search: `claude-3-5-sonnet-latest`, `claude-3-5-sonnet-20241022`, `claude-3-5-haiku-latest`, `claude-3-5-haiku-20241022`, `claude-3-7-sonnet-20250219`
|
||||
:::
|
||||
|
||||
## OpenAI Web Search: Two Approaches
|
||||
|
||||
OpenAI offers two distinct ways to use web search depending on the endpoint and model:
|
||||
|
||||
| Approach | Endpoint | Models | How to enable |
|
||||
|----------|----------|--------|---------------|
|
||||
| **Search Models** | `/chat/completions` | `gpt-5-search-api`, `gpt-4o-search-preview`, `gpt-4o-mini-search-preview` | Pass `web_search_options` parameter |
|
||||
| **Web Search Tool** | `/responses` | `gpt-5`, `gpt-4.1`, `gpt-4o`, and other regular models | Pass `web_search_preview` tool |
|
||||
|
||||
:::tip Search models search automatically
|
||||
Search models like `gpt-5-search-api` **automatically search the web** even without the `web_search_options` parameter. Use `web_search_options` to set `search_context_size` (`"low"`, `"medium"`, `"high"`) or specify `user_location` for localized results.
|
||||
:::
|
||||
|
||||
## `/chat/completions` (litellm.completion)
|
||||
|
||||
### Quick Start
|
||||
|
|
@ -39,7 +69,7 @@ Each provider uses their own search backend:
|
|||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="openai/gpt-4o-search-preview",
|
||||
model="openai/gpt-5-search-api",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
|
|
@ -59,31 +89,36 @@ response = completion(
|
|||
|
||||
```yaml
|
||||
model_list:
|
||||
# OpenAI
|
||||
# OpenAI search models
|
||||
- model_name: gpt-5-search-api
|
||||
litellm_params:
|
||||
model: openai/gpt-5-search-api
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
- model_name: gpt-4o-search-preview
|
||||
litellm_params:
|
||||
model: openai/gpt-4o-search-preview
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
|
||||
# xAI
|
||||
- model_name: grok-3
|
||||
litellm_params:
|
||||
model: xai/grok-3
|
||||
api_key: os.environ/XAI_API_KEY
|
||||
|
||||
|
||||
# Anthropic
|
||||
- model_name: claude-3-5-sonnet-latest
|
||||
litellm_params:
|
||||
model: anthropic/claude-3-5-sonnet-latest
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
|
||||
|
||||
# VertexAI
|
||||
- model_name: gemini-2-flash
|
||||
litellm_params:
|
||||
model: gemini-2.0-flash
|
||||
vertex_project: your-project-id
|
||||
vertex_location: us-central1
|
||||
|
||||
|
||||
# Google AI Studio
|
||||
- model_name: gemini-2-flash-studio
|
||||
litellm_params:
|
||||
|
|
@ -91,13 +126,13 @@ model_list:
|
|||
api_key: os.environ/GOOGLE_API_KEY
|
||||
```
|
||||
|
||||
2. Start the proxy
|
||||
2. Start the proxy
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
3. Test it!
|
||||
3. Test it!
|
||||
|
||||
```python showLineNumbers
|
||||
from openai import OpenAI
|
||||
|
|
@ -109,13 +144,18 @@ client = OpenAI(
|
|||
)
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="grok-3", # or any other web search enabled model
|
||||
model="gpt-5-search-api", # or any other web search enabled model
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What was a positive news story from today?"
|
||||
}
|
||||
]
|
||||
],
|
||||
extra_body={
|
||||
"web_search_options": {
|
||||
"search_context_size": "medium"
|
||||
}
|
||||
}
|
||||
)
|
||||
```
|
||||
</TabItem>
|
||||
|
|
@ -132,7 +172,7 @@ from litellm import completion
|
|||
|
||||
# Customize search context size
|
||||
response = completion(
|
||||
model="openai/gpt-4o-search-preview",
|
||||
model="openai/gpt-5-search-api",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
|
|
@ -240,6 +280,12 @@ response = client.chat.completions.create(
|
|||
|
||||
## `/responses` (litellm.responses)
|
||||
|
||||
Use the `web_search_preview` tool with models like `gpt-5`, `gpt-4.1`, `gpt-4o`, etc.
|
||||
|
||||
:::info
|
||||
Search-dedicated models like `gpt-5-search-api` and `gpt-4o-search-preview` do **not** support the `/responses` endpoint. Use them with `/chat/completions` + `web_search_options` instead (see above).
|
||||
:::
|
||||
|
||||
### Quick Start
|
||||
|
||||
<Tabs>
|
||||
|
|
@ -249,18 +295,14 @@ response = client.chat.completions.create(
|
|||
from litellm import responses
|
||||
|
||||
response = responses(
|
||||
model="openai/gpt-4o",
|
||||
input=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What was a positive news story from today?"
|
||||
}
|
||||
],
|
||||
model="openai/gpt-5",
|
||||
input="What is the capital of France?",
|
||||
tools=[{
|
||||
"type": "web_search_preview" # enables web search with default medium context size
|
||||
}]
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
|
|
@ -268,19 +310,24 @@ response = responses(
|
|||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-4o
|
||||
- model_name: gpt-5
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
model: openai/gpt-5
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
- model_name: gpt-4.1
|
||||
litellm_params:
|
||||
model: openai/gpt-4.1
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
```
|
||||
|
||||
2. Start the proxy
|
||||
2. Start the proxy
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
3. Test it!
|
||||
3. Test it!
|
||||
|
||||
```python showLineNumbers
|
||||
from openai import OpenAI
|
||||
|
|
@ -292,11 +339,11 @@ client = OpenAI(
|
|||
)
|
||||
|
||||
response = client.responses.create(
|
||||
model="gpt-4o",
|
||||
model="gpt-5",
|
||||
tools=[{
|
||||
"type": "web_search_preview"
|
||||
}],
|
||||
input="What was a positive news story from today?",
|
||||
input="What is the capital of France?",
|
||||
)
|
||||
|
||||
print(response.output_text)
|
||||
|
|
@ -314,13 +361,8 @@ from litellm import responses
|
|||
|
||||
# Customize search context size
|
||||
response = responses(
|
||||
model="openai/gpt-4o",
|
||||
input=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What was a positive news story from today?"
|
||||
}
|
||||
],
|
||||
model="openai/gpt-5",
|
||||
input="What is the capital of France?",
|
||||
tools=[{
|
||||
"type": "web_search_preview",
|
||||
"search_context_size": "low" # Options: "low", "medium" (default), "high"
|
||||
|
|
@ -341,12 +383,12 @@ client = OpenAI(
|
|||
|
||||
# Customize search context size
|
||||
response = client.responses.create(
|
||||
model="gpt-4o",
|
||||
model="gpt-5",
|
||||
tools=[{
|
||||
"type": "web_search_preview",
|
||||
"search_context_size": "low" # Options: "low", "medium" (default), "high"
|
||||
}],
|
||||
input="What was a positive news story from today?",
|
||||
input="What is the capital of France?",
|
||||
)
|
||||
|
||||
print(response.output_text)
|
||||
|
|
@ -400,14 +442,14 @@ model_list:
|
|||
web_search_options:
|
||||
search_context_size: "high" # Options: "low", "medium", "high"
|
||||
|
||||
# Different context size for different models
|
||||
- model_name: gpt-4o-search-preview
|
||||
# OpenAI search model with custom context size
|
||||
- model_name: gpt-5-search-api
|
||||
litellm_params:
|
||||
model: openai/gpt-4o-search-preview
|
||||
model: openai/gpt-5-search-api
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
web_search_options:
|
||||
search_context_size: "low"
|
||||
|
||||
|
||||
# Gemini with medium context (default)
|
||||
- model_name: gemini-2-flash
|
||||
litellm_params:
|
||||
|
|
@ -432,6 +474,7 @@ Use `litellm.supports_web_search(model="model_name")` -> returns `True` if model
|
|||
|
||||
```python showLineNumbers
|
||||
# Check OpenAI models
|
||||
assert litellm.supports_web_search(model="openai/gpt-5-search-api") == True
|
||||
assert litellm.supports_web_search(model="openai/gpt-4o-search-preview") == True
|
||||
|
||||
# Check xAI models
|
||||
|
|
@ -455,13 +498,20 @@ assert litellm.supports_web_search(model="gemini/gemini-2.0-flash") == True
|
|||
```yaml
|
||||
model_list:
|
||||
# OpenAI
|
||||
- model_name: gpt-5-search-api
|
||||
litellm_params:
|
||||
model: openai/gpt-5-search-api
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
model_info:
|
||||
supports_web_search: True
|
||||
|
||||
- model_name: gpt-4o-search-preview
|
||||
litellm_params:
|
||||
model: openai/gpt-4o-search-preview
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
model_info:
|
||||
supports_web_search: True
|
||||
|
||||
|
||||
# xAI
|
||||
- model_name: grok-3
|
||||
litellm_params:
|
||||
|
|
@ -516,6 +566,12 @@ Expected Response
|
|||
```json showLineNumbers
|
||||
{
|
||||
"data": [
|
||||
{
|
||||
"model_group": "gpt-5-search-api",
|
||||
"providers": ["openai"],
|
||||
"max_tokens": 128000,
|
||||
"supports_web_search": true
|
||||
},
|
||||
{
|
||||
"model_group": "gpt-4o-search-preview",
|
||||
"providers": ["openai"],
|
||||
|
|
|
|||
|
|
@ -1,27 +1,36 @@
|
|||
# Contributing Code
|
||||
|
||||
## **Checklist before submitting a PR**
|
||||
## Checklist before submitting a PR
|
||||
|
||||
Here are the core requirements for any PR submitted to LiteLLM
|
||||
Here are the core requirements for any PR submitted to LiteLLM:
|
||||
|
||||
- [ ] Sign the Contributor License Agreement (CLA) - [see details](#contributor-license-agreement-cla)
|
||||
- [ ] Add testing, **Adding at least 1 test is a hard requirement** - [see details](#2-adding-testing-to-your-pr)
|
||||
- [ ] Ensure your PR passes the following tests:
|
||||
- [ ] [Unit Tests](#3-running-unit-tests)
|
||||
- [ ] [Formatting / Linting Tests](#35-running-linting-tests)
|
||||
- [ ] Keep scope as isolated as possible. As a general rule, your changes should address 1 specific problem at a time
|
||||
- [ ] Sign the [Contributor License Agreement (CLA)](#contributor-license-agreement-cla)
|
||||
- [ ] Keep scope as isolated as possible — your changes should address **one specific problem** at a time
|
||||
|
||||
## **Contributor License Agreement (CLA)**
|
||||
### Proxy (Backend) PRs
|
||||
|
||||
- [ ] Add testing — **at least 1 test is a hard requirement** ([details](#2-adding-tests))
|
||||
- [ ] Ensure your PR passes:
|
||||
- [ ] [Unit Tests](#3-running-unit-tests) — `make test-unit`
|
||||
- [ ] [Formatting / Linting Tests](#4-running-linting-tests) — `make lint`
|
||||
|
||||
### UI PRs
|
||||
|
||||
- [ ] Ensure the UI builds successfully — `npm run build`
|
||||
- [ ] Ensure all UI unit tests pass — `npm run test`
|
||||
- [ ] If you are adding a **new component** or **new logic**, add corresponding tests
|
||||
|
||||
## Contributor License Agreement (CLA)
|
||||
|
||||
Before contributing code to LiteLLM, you must sign our [Contributor License Agreement (CLA)](https://cla-assistant.io/BerriAI/litellm). This is a legal requirement for all contributions to be merged into the main repository. The CLA helps protect both you and the project by clearly defining the terms under which your contributions are made.
|
||||
|
||||
**Important:** We strongly recommend reviewing and signing the CLA before starting work on your contribution to avoid any delays in the PR process. You can find the CLA [here](https://cla-assistant.io/BerriAI/litellm) and sign it through our CLA management system when you submit your first PR.
|
||||
**Important:** We strongly recommend signing the CLA **before** starting work on your contribution to avoid delays in the review process. You can find and sign the CLA [here](https://cla-assistant.io/BerriAI/litellm).
|
||||
|
||||
## Quick start
|
||||
---
|
||||
|
||||
## 1. Setup your local dev environment
|
||||
## Proxy (Backend)
|
||||
|
||||
Here's how to modify the repo locally:
|
||||
### 1. Setting up your local dev environment
|
||||
|
||||
Step 1: Clone the repo
|
||||
|
||||
|
|
@ -29,56 +38,53 @@ Step 1: Clone the repo
|
|||
git clone https://github.com/BerriAI/litellm.git
|
||||
```
|
||||
|
||||
Step 2: Install dev dependencies:
|
||||
Step 2: Install dev dependencies
|
||||
|
||||
```shell
|
||||
poetry install --with dev --extras proxy
|
||||
```
|
||||
|
||||
That's it, your local dev environment is ready!
|
||||
### 2. Adding tests
|
||||
|
||||
## 2. Adding Testing to your PR
|
||||
- Add your tests to the [`tests/test_litellm/` directory](https://github.com/BerriAI/litellm/tree/main/tests/litellm).
|
||||
- This directory mirrors the `litellm/` directory 1:1 and should **only** contain mocked tests.
|
||||
- **Do not** add real LLM API calls to this directory.
|
||||
|
||||
- Add your test to the [`tests/test_litellm/` directory](https://github.com/BerriAI/litellm/tree/main/tests/litellm)
|
||||
#### File naming convention for `tests/test_litellm/`
|
||||
|
||||
- This directory 1:1 maps the the `litellm/` directory, and can only contain mocked tests.
|
||||
- Do not add real llm api calls to this directory.
|
||||
The test directory follows the same structure as `litellm/`:
|
||||
|
||||
### 2.1 File Naming Convention for `tests/test_litellm/`
|
||||
|
||||
The `tests/test_litellm/` directory follows the same directory structure as `litellm/`.
|
||||
|
||||
- `litellm/proxy/test_caching_routes.py` maps to `litellm/proxy/caching_routes.py`
|
||||
- `test_{filename}.py` maps to `litellm/{filename}.py`
|
||||
- `litellm/proxy/test_caching_routes.py` maps to `litellm/proxy/caching_routes.py`
|
||||
|
||||
## 3. Running Unit Tests
|
||||
### 3. Running unit tests
|
||||
|
||||
run the following command on the root of the litellm directory
|
||||
Run the following command from the root of the `litellm` directory:
|
||||
|
||||
```shell
|
||||
make test-unit
|
||||
```
|
||||
|
||||
## 3.5 Running Linting Tests
|
||||
### 4. Running linting tests
|
||||
|
||||
run the following command on the root of the litellm directory
|
||||
Run the following command from the root of the `litellm` directory:
|
||||
|
||||
```shell
|
||||
make lint
|
||||
```
|
||||
|
||||
LiteLLM uses mypy for linting. On ci/cd we also run `black` for formatting.
|
||||
LiteLLM uses `mypy` for type checking. CI/CD also runs `black` for formatting.
|
||||
|
||||
## 4. Submit a PR with your changes!
|
||||
### 5. Submit a PR
|
||||
|
||||
- push your fork to your GitHub repo
|
||||
- submit a PR from there
|
||||
- Push your changes to your fork on GitHub
|
||||
- Open a Pull Request from your fork
|
||||
|
||||
## Advanced
|
||||
---
|
||||
|
||||
### Building LiteLLM Docker Image
|
||||
## UI
|
||||
|
||||
Some people might want to build the LiteLLM docker image themselves. Follow these instructions if you want to build / run the LiteLLM Docker Image yourself.
|
||||
### 1. Setting up your local dev environment
|
||||
|
||||
Step 1: Clone the repo
|
||||
|
||||
|
|
@ -86,17 +92,72 @@ Step 1: Clone the repo
|
|||
git clone https://github.com/BerriAI/litellm.git
|
||||
```
|
||||
|
||||
Step 2: Build the Docker Image
|
||||
Step 2: Navigate to the UI dashboard directory
|
||||
|
||||
Build using Dockerfile.non_root
|
||||
```shell
|
||||
cd ui/litellm-dashboard
|
||||
```
|
||||
|
||||
Step 3: Install dependencies
|
||||
|
||||
```shell
|
||||
npm install
|
||||
```
|
||||
|
||||
Step 4: Start the development server
|
||||
|
||||
```shell
|
||||
npm run dev
|
||||
```
|
||||
|
||||
### 2. Adding tests
|
||||
|
||||
If you are adding a **new component** or **new logic**, you must add corresponding tests.
|
||||
|
||||
### 3. Running UI unit tests
|
||||
|
||||
```shell
|
||||
npm run test
|
||||
```
|
||||
|
||||
### 4. Building the UI
|
||||
|
||||
Ensure the UI builds successfully before submitting your PR:
|
||||
|
||||
```shell
|
||||
npm run build
|
||||
```
|
||||
|
||||
### 5. Submit a PR
|
||||
|
||||
- Push your changes to your fork on GitHub
|
||||
- Open a Pull Request from your fork
|
||||
|
||||
---
|
||||
|
||||
## Advanced
|
||||
|
||||
### Building the LiteLLM Docker Image
|
||||
|
||||
Follow these instructions if you want to build and run the LiteLLM Docker image yourself.
|
||||
|
||||
Step 1: Clone the repo
|
||||
|
||||
```shell
|
||||
git clone https://github.com/BerriAI/litellm.git
|
||||
```
|
||||
|
||||
Step 2: Build the Docker image
|
||||
|
||||
Build using `Dockerfile.non_root`:
|
||||
|
||||
```shell
|
||||
docker build -f docker/Dockerfile.non_root -t litellm_test_image .
|
||||
```
|
||||
|
||||
Step 3: Run the Docker Image
|
||||
Step 3: Run the Docker image
|
||||
|
||||
Make sure config.yaml is present in the root directory. This is your litellm proxy config file.
|
||||
Make sure `config.yaml` is present in the root directory. This is your LiteLLM proxy config file.
|
||||
|
||||
```shell
|
||||
docker run \
|
||||
|
|
@ -107,18 +168,19 @@ docker run \
|
|||
litellm_test_image \
|
||||
--config /app/config.yaml --detailed_debug
|
||||
```
|
||||
### Running LiteLLM Proxy Locally
|
||||
|
||||
1. cd into the `proxy/` directory
|
||||
### Running the LiteLLM Proxy Locally
|
||||
|
||||
```
|
||||
1. Navigate to the `proxy/` directory:
|
||||
|
||||
```shell
|
||||
cd litellm/litellm/proxy
|
||||
```
|
||||
|
||||
2. Run the proxy
|
||||
2. Run the proxy:
|
||||
|
||||
```shell
|
||||
python3 proxy_cli.py --config /path/to/config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
```
|
||||
|
|
|
|||
411
docs/my-website/docs/integrations/websearch_interception.md
Normal file
|
|
@ -0,0 +1,411 @@
|
|||
# Web Search Integration
|
||||
|
||||
Enable transparent server-side web search execution for any LLM provider. LiteLLM automatically intercepts web search tool calls and executes them using your configured search provider (Perplexity, Tavily, etc.).
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Configure Web Search Interception
|
||||
|
||||
Add to your `config.yaml`:
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-4o
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
litellm_settings:
|
||||
callbacks:
|
||||
- websearch_interception:
|
||||
enabled_providers:
|
||||
- openai
|
||||
- minimax
|
||||
- anthropic
|
||||
search_tool_name: perplexity-search # Optional
|
||||
|
||||
search_tools:
|
||||
- search_tool_name: perplexity-search
|
||||
litellm_params:
|
||||
search_provider: perplexity
|
||||
api_key: os.environ/PERPLEXITY_API_KEY
|
||||
```
|
||||
|
||||
### 2. Use with Any Provider
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = await litellm.acompletion(
|
||||
model="gpt-4o",
|
||||
messages=[
|
||||
{"role": "user", "content": "What's the weather in San Francisco today?"}
|
||||
],
|
||||
tools=[
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "litellm_web_search",
|
||||
"description": "Search the web for information",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"query": {"type": "string", "description": "Search query"}
|
||||
},
|
||||
"required": ["query"]
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
)
|
||||
|
||||
# Response includes search results automatically!
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
## How It Works
|
||||
|
||||
When a model makes a web search tool call, LiteLLM:
|
||||
|
||||
1. **Detects** the `litellm_web_search` tool call in the response
|
||||
2. **Executes** the search using your configured search provider
|
||||
3. **Makes a follow-up request** with the search results
|
||||
4. **Returns** the final answer to the user
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant User
|
||||
participant LiteLLM
|
||||
participant LLM as LLM Provider
|
||||
participant Search as Search Provider
|
||||
|
||||
User->>LiteLLM: Request with web_search tool
|
||||
LiteLLM->>LLM: Forward request
|
||||
LLM-->>LiteLLM: Response with tool_call
|
||||
Note over LiteLLM: Detect web search<br/>tool call
|
||||
LiteLLM->>Search: Execute search
|
||||
Search-->>LiteLLM: Search results
|
||||
LiteLLM->>LLM: Follow-up with results
|
||||
LLM-->>LiteLLM: Final answer
|
||||
LiteLLM-->>User: Final answer with search results
|
||||
```
|
||||
|
||||
**Result**: One API call from user → Complete answer with search results
|
||||
|
||||
## Supported Providers
|
||||
|
||||
Web search integration works with **all providers** that use:
|
||||
- ✅ **Base HTTP Handler** (`BaseLLMHTTPHandler`)
|
||||
- ✅ **OpenAI Completion Handler** (`OpenAIChatCompletion`)
|
||||
|
||||
### Providers Using Base HTTP Handler
|
||||
|
||||
| Provider | Status | Notes |
|
||||
|----------|--------|-------|
|
||||
| **OpenAI** | ✅ Supported | GPT-4, GPT-3.5, etc. |
|
||||
| **Anthropic** | ✅ Supported | Claude models via HTTP handler |
|
||||
| **MiniMax** | ✅ Supported | All MiniMax models |
|
||||
| **Mistral** | ✅ Supported | Mistral AI models |
|
||||
| **Cohere** | ✅ Supported | Command models |
|
||||
| **Fireworks AI** | ✅ Supported | All Fireworks models |
|
||||
| **Together AI** | ✅ Supported | All Together AI models |
|
||||
| **Groq** | ✅ Supported | All Groq models |
|
||||
| **Perplexity** | ✅ Supported | Perplexity models |
|
||||
| **DeepSeek** | ✅ Supported | DeepSeek models |
|
||||
| **xAI** | ✅ Supported | Grok models |
|
||||
| **Hugging Face** | ✅ Supported | Inference API models |
|
||||
| **OCI** | ✅ Supported | Oracle Cloud models |
|
||||
| **Vertex AI** | ✅ Supported | Google Vertex AI models |
|
||||
| **Bedrock** | ✅ Supported | AWS Bedrock models (converse_like route) |
|
||||
| **Azure OpenAI** | ✅ Supported | Azure-hosted OpenAI models |
|
||||
| **Sagemaker** | ✅ Supported | AWS Sagemaker models |
|
||||
| **Databricks** | ✅ Supported | Databricks models |
|
||||
| **DataRobot** | ✅ Supported | DataRobot models |
|
||||
| **Hosted VLLM** | ✅ Supported | Self-hosted VLLM |
|
||||
| **Heroku** | ✅ Supported | Heroku-hosted models |
|
||||
| **RAGFlow** | ✅ Supported | RAGFlow models |
|
||||
| **Compactif** | ✅ Supported | Compactif models |
|
||||
| **Cometapi** | ✅ Supported | Comet API models |
|
||||
| **A2A** | ✅ Supported | Agent-to-Agent models |
|
||||
| **Bytez** | ✅ Supported | Bytez models |
|
||||
|
||||
### Providers Using OpenAI Handler
|
||||
|
||||
| Provider | Status | Notes |
|
||||
|----------|--------|-------|
|
||||
| **OpenAI** | ✅ Supported | Native OpenAI API |
|
||||
| **Azure OpenAI** | ✅ Supported | Azure-hosted OpenAI |
|
||||
| **OpenAI-Compatible** | ✅ Supported | Any OpenAI-compatible API |
|
||||
|
||||
## Configuration
|
||||
|
||||
### WebSearch Interception Parameters
|
||||
|
||||
| Parameter | Type | Required | Description | Example |
|
||||
|-----------|------|----------|-------------|---------|
|
||||
| `enabled_providers` | List[String] | Yes | List of providers to enable web search for | `[openai, minimax, anthropic]` |
|
||||
| `search_tool_name` | String | No | Specific search tool from `search_tools` config. If not set, uses first available. | `perplexity-search` |
|
||||
|
||||
### Provider Values
|
||||
|
||||
Use these values in `enabled_providers`:
|
||||
|
||||
| Provider | Value | Provider | Value |
|
||||
|----------|-------|----------|-------|
|
||||
| OpenAI | `openai` | Anthropic | `anthropic` |
|
||||
| MiniMax | `minimax` | Mistral | `mistral` |
|
||||
| Cohere | `cohere` | Fireworks AI | `fireworks_ai` |
|
||||
| Together AI | `together_ai` | Groq | `groq` |
|
||||
| Perplexity | `perplexity` | DeepSeek | `deepseek` |
|
||||
| xAI | `xai` | Hugging Face | `huggingface` |
|
||||
| OCI | `oci` | Vertex AI | `vertex_ai` |
|
||||
| Bedrock | `bedrock` | Azure | `azure` |
|
||||
| Sagemaker | `sagemaker_chat` | Databricks | `databricks` |
|
||||
| DataRobot | `datarobot` | VLLM | `hosted_vllm` |
|
||||
| Heroku | `heroku` | RAGFlow | `ragflow` |
|
||||
| Compactif | `compactif` | Cometapi | `cometapi` |
|
||||
| A2A | `a2a` | Bytez | `bytez` |
|
||||
|
||||
## Search Providers
|
||||
|
||||
Configure which search provider to use. LiteLLM supports multiple search providers:
|
||||
|
||||
| Provider | `search_provider` Value | Environment Variable |
|
||||
|----------|------------------------|----------------------|
|
||||
| **Perplexity AI** | `perplexity` | `PERPLEXITYAI_API_KEY` |
|
||||
| **Tavily** | `tavily` | `TAVILY_API_KEY` |
|
||||
| **Exa AI** | `exa_ai` | `EXA_API_KEY` |
|
||||
| **Parallel AI** | `parallel_ai` | `PARALLEL_AI_API_KEY` |
|
||||
| **Google PSE** | `google_pse` | `GOOGLE_PSE_API_KEY`, `GOOGLE_PSE_ENGINE_ID` |
|
||||
| **DataForSEO** | `dataforseo` | `DATAFORSEO_LOGIN`, `DATAFORSEO_PASSWORD` |
|
||||
| **Firecrawl** | `firecrawl` | `FIRECRAWL_API_KEY` |
|
||||
| **SearXNG** | `searxng` | `SEARXNG_API_BASE` (required) |
|
||||
| **Linkup** | `linkup` | `LINKUP_API_KEY` |
|
||||
|
||||
See [Search Providers Documentation](../search/index.md) for detailed setup instructions.
|
||||
|
||||
## Complete Configuration Example
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
# OpenAI
|
||||
- model_name: gpt-4o
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
# MiniMax
|
||||
- model_name: minimax
|
||||
litellm_params:
|
||||
model: minimax/MiniMax-M2.1
|
||||
api_key: os.environ/MINIMAX_API_KEY
|
||||
|
||||
# Anthropic
|
||||
- model_name: claude
|
||||
litellm_params:
|
||||
model: anthropic/claude-sonnet-4-5
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
|
||||
# Azure OpenAI
|
||||
- model_name: azure-gpt4
|
||||
litellm_params:
|
||||
model: azure/gpt-4
|
||||
api_base: https://my-azure.openai.azure.com
|
||||
api_key: os.environ/AZURE_API_KEY
|
||||
|
||||
litellm_settings:
|
||||
callbacks:
|
||||
- websearch_interception:
|
||||
enabled_providers:
|
||||
- openai
|
||||
- minimax
|
||||
- anthropic
|
||||
- azure
|
||||
search_tool_name: perplexity-search
|
||||
|
||||
search_tools:
|
||||
- search_tool_name: perplexity-search
|
||||
litellm_params:
|
||||
search_provider: perplexity
|
||||
api_key: os.environ/PERPLEXITY_API_KEY
|
||||
|
||||
- search_tool_name: tavily-search
|
||||
litellm_params:
|
||||
search_provider: tavily
|
||||
api_key: os.environ/TAVILY_API_KEY
|
||||
```
|
||||
|
||||
## Usage Examples
|
||||
|
||||
### Python SDK
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
# Configure callbacks
|
||||
litellm.callbacks = ["websearch_interception"]
|
||||
|
||||
# Make completion with web search tool
|
||||
response = await litellm.acompletion(
|
||||
model="gpt-4o",
|
||||
messages=[
|
||||
{"role": "user", "content": "What are the latest AI news?"}
|
||||
],
|
||||
tools=[
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "litellm_web_search",
|
||||
"description": "Search the web for current information",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"query": {
|
||||
"type": "string",
|
||||
"description": "Search query"
|
||||
}
|
||||
},
|
||||
"required": ["query"]
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
### Proxy Server
|
||||
|
||||
```bash
|
||||
# Start proxy with config
|
||||
litellm --config config.yaml
|
||||
|
||||
# Make request
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gpt-4o",
|
||||
"messages": [
|
||||
{"role": "user", "content": "What is the weather in San Francisco?"}
|
||||
],
|
||||
"tools": [
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "litellm_web_search",
|
||||
"description": "Search the web",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"query": {"type": "string"}
|
||||
},
|
||||
"required": ["query"]
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
## How Search Tool Selection Works
|
||||
|
||||
1. **If `search_tool_name` is specified** → Uses that specific search tool
|
||||
2. **If `search_tool_name` is not specified** → Uses first search tool in `search_tools` list
|
||||
|
||||
```yaml
|
||||
search_tools:
|
||||
- search_tool_name: perplexity-search # ← This will be used if no search_tool_name specified
|
||||
litellm_params:
|
||||
search_provider: perplexity
|
||||
api_key: os.environ/PERPLEXITY_API_KEY
|
||||
|
||||
- search_tool_name: tavily-search
|
||||
litellm_params:
|
||||
search_provider: tavily
|
||||
api_key: os.environ/TAVILY_API_KEY
|
||||
```
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
### Web Search Not Working
|
||||
|
||||
1. **Check provider is enabled**:
|
||||
```yaml
|
||||
enabled_providers:
|
||||
- openai # Make sure your provider is in this list
|
||||
```
|
||||
|
||||
2. **Verify search tool is configured**:
|
||||
```yaml
|
||||
search_tools:
|
||||
- search_tool_name: perplexity-search
|
||||
litellm_params:
|
||||
search_provider: perplexity
|
||||
api_key: os.environ/PERPLEXITY_API_KEY
|
||||
```
|
||||
|
||||
3. **Check API keys are set**:
|
||||
```bash
|
||||
export PERPLEXITY_API_KEY=your-key
|
||||
```
|
||||
|
||||
4. **Enable debug logging**:
|
||||
```python
|
||||
litellm.set_verbose = True
|
||||
```
|
||||
|
||||
### Common Issues
|
||||
|
||||
**Issue**: Model returns tool_calls instead of final answer
|
||||
- **Cause**: Provider not in `enabled_providers` list
|
||||
- **Solution**: Add provider to `enabled_providers`
|
||||
|
||||
**Issue**: "No search tool configured" error
|
||||
- **Cause**: No search tools in `search_tools` config
|
||||
- **Solution**: Add at least one search tool configuration
|
||||
|
||||
**Issue**: "Invalid function arguments json string" error (MiniMax)
|
||||
- **Cause**: Fixed in latest version - arguments weren't properly JSON serialized
|
||||
- **Solution**: Update to latest LiteLLM version
|
||||
|
||||
## Related Documentation
|
||||
|
||||
- [Search Providers](../search/index.md) - Detailed search provider setup
|
||||
- [Claude Code WebSearch](../tutorials/claude_code_websearch.md) - Using with Claude Code
|
||||
- [Tool Calling](../completion/function_call.md) - General tool calling documentation
|
||||
- [Callbacks](./custom_callback.md) - Custom callback documentation
|
||||
|
||||
## Technical Details
|
||||
|
||||
### Architecture
|
||||
|
||||
Web search integration is implemented as a custom callback (`WebSearchInterceptionLogger`) that:
|
||||
|
||||
1. **Pre-request Hook**: Converts native web search tools to LiteLLM standard format
|
||||
2. **Post-response Hook**: Detects web search tool calls in responses
|
||||
3. **Agentic Loop**: Executes searches and makes follow-up requests automatically
|
||||
|
||||
### Supported APIs
|
||||
|
||||
- ✅ **Chat Completions API** (OpenAI format)
|
||||
- ✅ **Anthropic Messages API** (Anthropic format)
|
||||
- ✅ **Streaming** (automatically converted)
|
||||
- ✅ **Non-streaming**
|
||||
|
||||
### Response Format Detection
|
||||
|
||||
The handler automatically detects response format:
|
||||
- **OpenAI format**: `tool_calls` in assistant message
|
||||
- **Anthropic format**: `tool_use` blocks in content
|
||||
|
||||
### Performance
|
||||
|
||||
- **Latency**: Adds one additional LLM call (follow-up request with search results)
|
||||
- **Caching**: Search results can be cached (depends on search provider)
|
||||
- **Parallel Searches**: Multiple search queries executed in parallel
|
||||
|
||||
## Contributing
|
||||
|
||||
Found a bug or want to add support for a new provider? See our [Contributing Guide](https://github.com/BerriAI/litellm/blob/main/CONTRIBUTING.md).
|
||||
|
|
@ -4,8 +4,9 @@ import Image from '@theme/IdealImage';
|
|||
|
||||
## Locust Load Test LiteLLM Proxy
|
||||
|
||||
1. Add `fake-openai-endpoint` to your proxy config.yaml and start your litellm proxy
|
||||
litellm provides a free hosted `fake-openai-endpoint` you can load test against
|
||||
1. Add `fake-openai-endpoint` to your proxy config.yaml and start your litellm proxy.
|
||||
|
||||
LiteLLM provides a free hosted `fake-openai-endpoint` you can load test against. You can also self-host your own fake OpenAI proxy server using [github.com/BerriAI/example_openai_endpoint](https://github.com/BerriAI/example_openai_endpoint).
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
|
|
|
|||
|
|
@ -29,12 +29,16 @@ Tutorial on how to get to 1K+ RPS with LiteLLM Proxy on locust
|
|||
|
||||
**Note:** we're currently migrating to aiohttp which has 10x higher throughput. We recommend using the `openai/` provider for load testing.
|
||||
|
||||
:::tip Setting Up a Fake OpenAI Endpoint
|
||||
You can use our hosted fake endpoint or self-host your own using [github.com/BerriAI/example_openai_endpoint](https://github.com/BerriAI/example_openai_endpoint).
|
||||
:::
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: "fake-openai-endpoint"
|
||||
litellm_params:
|
||||
model: openai/any
|
||||
api_base: https://your-fake-openai-endpoint.com/chat/completions
|
||||
api_base: https://exampleopenaiendpoint-production.up.railway.app/ # or your self-hosted endpoint
|
||||
api_key: "test"
|
||||
```
|
||||
|
||||
|
|
|
|||
|
|
@ -506,7 +506,14 @@ Your OpenAPI specification should follow standard OpenAPI/Swagger conventions:
|
|||
- **Operation IDs**: Each operation should have a unique `operationId` (this becomes the tool name)
|
||||
- **Parameters**: Request parameters should be properly documented with types and descriptions
|
||||
|
||||
## MCP Oauth
|
||||
## MCP OAuth
|
||||
|
||||
LiteLLM supports OAuth 2.0 for MCP servers -- both interactive (PKCE) flows for user-facing clients and machine-to-machine (M2M) `client_credentials` for backend services.
|
||||
|
||||
See the **[MCP OAuth guide](./mcp_oauth.md)** for setup instructions, sequence diagrams, and a test server.
|
||||
|
||||
<details>
|
||||
<summary>Detailed OAuth reference (click to expand)</summary>
|
||||
|
||||
LiteLLM v 1.77.6 added support for OAuth 2.0 Client Credentials for MCP servers.
|
||||
|
||||
|
|
@ -588,6 +595,8 @@ sequenceDiagram
|
|||
|
||||
See the official [MCP Authorization Flow](https://modelcontextprotocol.io/specification/2025-06-18/basic/authorization#authorization-flow-steps) for additional reference.
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
## Forwarding Custom Headers to MCP Servers
|
||||
|
||||
|
|
@ -1486,7 +1495,7 @@ async with stdio_client(server_params) as (read, write):
|
|||
|
||||
**Q: How do I use OAuth2 client_credentials (machine-to-machine) with MCP servers behind LiteLLM?**
|
||||
|
||||
At the moment LiteLLM only forwards whatever `Authorization` header/value you configure for the MCP server; it does not issue OAuth2 tokens by itself. If your MCP requires the Client Credentials grant, obtain the access token directly from the authorization server and set that bearer token as the MCP server’s Authorization header value. LiteLLM does not yet fetch or refresh those machine-to-machine tokens on your behalf, but we plan to add first-class client_credentials support in a future release so the proxy can manage those tokens automatically.
|
||||
LiteLLM supports automatic token management for the `client_credentials` grant. Configure `client_id`, `client_secret`, and `token_url` on your MCP server and LiteLLM will fetch, cache, and refresh tokens automatically. See the [MCP OAuth M2M guide](./mcp_oauth.md#machine-to-machine-m2m-auth) for setup instructions.
|
||||
|
||||
**Q: When I fetch an OAuth token from the LiteLLM UI, where is it stored?**
|
||||
|
||||
|
|
|
|||
337
docs/my-website/docs/mcp_oauth.md
Normal file
|
|
@ -0,0 +1,337 @@
|
|||
# MCP OAuth
|
||||
|
||||
LiteLLM supports two OAuth 2.0 flows for MCP servers:
|
||||
|
||||
| Flow | Use Case | How It Works |
|
||||
|------|----------|--------------|
|
||||
| **Interactive (PKCE)** | User-facing apps (Claude Code, Cursor) | Browser-based consent, per-user tokens |
|
||||
| **Machine-to-Machine (M2M)** | Backend services, CI/CD, automated agents | `client_credentials` grant, proxy-managed tokens |
|
||||
|
||||
## Interactive OAuth (PKCE)
|
||||
|
||||
For user-facing MCP clients (Claude Code, Cursor), LiteLLM supports the full OAuth 2.0 authorization code flow with PKCE.
|
||||
|
||||
### Setup
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
mcp_servers:
|
||||
github_mcp:
|
||||
url: "https://api.githubcopilot.com/mcp"
|
||||
auth_type: oauth2
|
||||
client_id: os.environ/GITHUB_OAUTH_CLIENT_ID
|
||||
client_secret: os.environ/GITHUB_OAUTH_CLIENT_SECRET
|
||||
```
|
||||
|
||||
[**See Claude Code Tutorial**](./tutorials/claude_responses_api#connecting-mcp-servers)
|
||||
|
||||
### How It Works
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant Browser as User-Agent (Browser)
|
||||
participant Client as Client
|
||||
participant LiteLLM as LiteLLM Proxy
|
||||
participant MCP as MCP Server (Resource Server)
|
||||
participant Auth as Authorization Server
|
||||
|
||||
Note over Client,LiteLLM: Step 1 – Resource discovery
|
||||
Client->>LiteLLM: GET /.well-known/oauth-protected-resource/{mcp_server_name}/mcp
|
||||
LiteLLM->>Client: Return resource metadata
|
||||
|
||||
Note over Client,LiteLLM: Step 2 – Authorization server discovery
|
||||
Client->>LiteLLM: GET /.well-known/oauth-authorization-server/{mcp_server_name}
|
||||
LiteLLM->>Client: Return authorization server metadata
|
||||
|
||||
Note over Client,Auth: Step 3 – Dynamic client registration
|
||||
Client->>LiteLLM: POST /{mcp_server_name}/register
|
||||
LiteLLM->>Auth: Forward registration request
|
||||
Auth->>LiteLLM: Issue client credentials
|
||||
LiteLLM->>Client: Return client credentials
|
||||
|
||||
Note over Client,Browser: Step 4 – User authorization (PKCE)
|
||||
Client->>Browser: Open authorization URL + code_challenge + resource
|
||||
Browser->>Auth: Authorization request
|
||||
Note over Auth: User authorizes
|
||||
Auth->>Browser: Redirect with authorization code
|
||||
Browser->>LiteLLM: Callback to LiteLLM with code
|
||||
LiteLLM->>Browser: Redirect back with authorization code
|
||||
Browser->>Client: Callback with authorization code
|
||||
|
||||
Note over Client,Auth: Step 5 – Token exchange
|
||||
Client->>LiteLLM: Token request + code_verifier + resource
|
||||
LiteLLM->>Auth: Forward token request
|
||||
Auth->>LiteLLM: Access (and refresh) token
|
||||
LiteLLM->>Client: Return tokens
|
||||
|
||||
Note over Client,MCP: Step 6 – Authenticated MCP call
|
||||
Client->>LiteLLM: MCP request with access token + LiteLLM API key
|
||||
LiteLLM->>MCP: MCP request with Bearer token
|
||||
MCP-->>LiteLLM: MCP response
|
||||
LiteLLM-->>Client: Return MCP response
|
||||
```
|
||||
|
||||
**Participants**
|
||||
|
||||
- **Client** -- The MCP-capable AI agent (e.g., Claude Code, Cursor, or another IDE/agent) that initiates OAuth discovery, authorization, and tool invocations on behalf of the user.
|
||||
- **LiteLLM Proxy** -- Mediates all OAuth discovery, registration, token exchange, and MCP traffic while protecting stored credentials.
|
||||
- **Authorization Server** -- Issues OAuth 2.0 tokens via dynamic client registration, PKCE authorization, and token endpoints.
|
||||
- **MCP Server (Resource Server)** -- The protected MCP endpoint that receives LiteLLM's authenticated JSON-RPC requests.
|
||||
- **User-Agent (Browser)** -- Temporarily involved so the end user can grant consent during the authorization step.
|
||||
|
||||
**Flow Steps**
|
||||
|
||||
1. **Resource Discovery**: The client fetches MCP resource metadata from LiteLLM's `.well-known/oauth-protected-resource` endpoint to understand scopes and capabilities.
|
||||
2. **Authorization Server Discovery**: The client retrieves the OAuth server metadata (token endpoint, authorization endpoint, supported PKCE methods) through LiteLLM's `.well-known/oauth-authorization-server` endpoint.
|
||||
3. **Dynamic Client Registration**: The client registers through LiteLLM, which forwards the request to the authorization server (RFC 7591). If the provider doesn't support dynamic registration, you can pre-store `client_id`/`client_secret` in LiteLLM (e.g., GitHub MCP) and the flow proceeds the same way.
|
||||
4. **User Authorization**: The client launches a browser session (with code challenge and resource hints). The user approves access, the authorization server sends the code through LiteLLM back to the client.
|
||||
5. **Token Exchange**: The client calls LiteLLM with the authorization code, code verifier, and resource. LiteLLM exchanges them with the authorization server and returns the issued access/refresh tokens.
|
||||
6. **MCP Invocation**: With a valid token, the client sends the MCP JSON-RPC request (plus LiteLLM API key) to LiteLLM, which forwards it to the MCP server and relays the tool response.
|
||||
|
||||
See the official [MCP Authorization Flow](https://modelcontextprotocol.io/specification/2025-06-18/basic/authorization#authorization-flow-steps) for additional reference.
|
||||
|
||||
## Machine-to-Machine (M2M) Auth
|
||||
|
||||
LiteLLM automatically fetches, caches, and refreshes OAuth2 tokens using the `client_credentials` grant. No manual token management required.
|
||||
|
||||
### Setup
|
||||
|
||||
You can configure M2M OAuth via the LiteLLM UI or `config.yaml`.
|
||||
|
||||
### UI Setup
|
||||
|
||||
Navigate to the **MCP Servers** page and click **+ Add New MCP Server**.
|
||||
|
||||
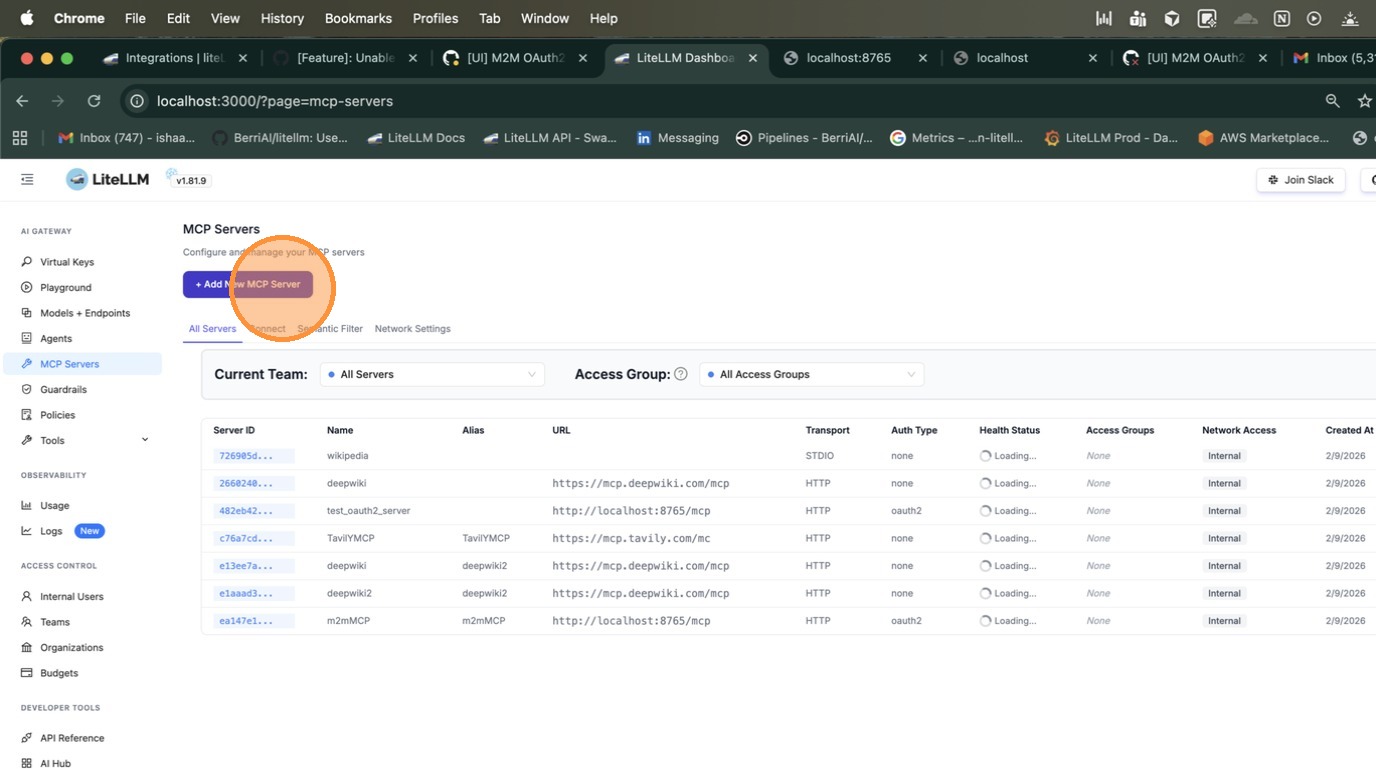
|
||||
|
||||
Enter a name for your server and select **HTTP** as the transport type.
|
||||
|
||||
|
||||
|
||||
Paste the MCP server URL.
|
||||
|
||||
|
||||
|
||||
Under **Authentication**, select **OAuth**.
|
||||
|
||||
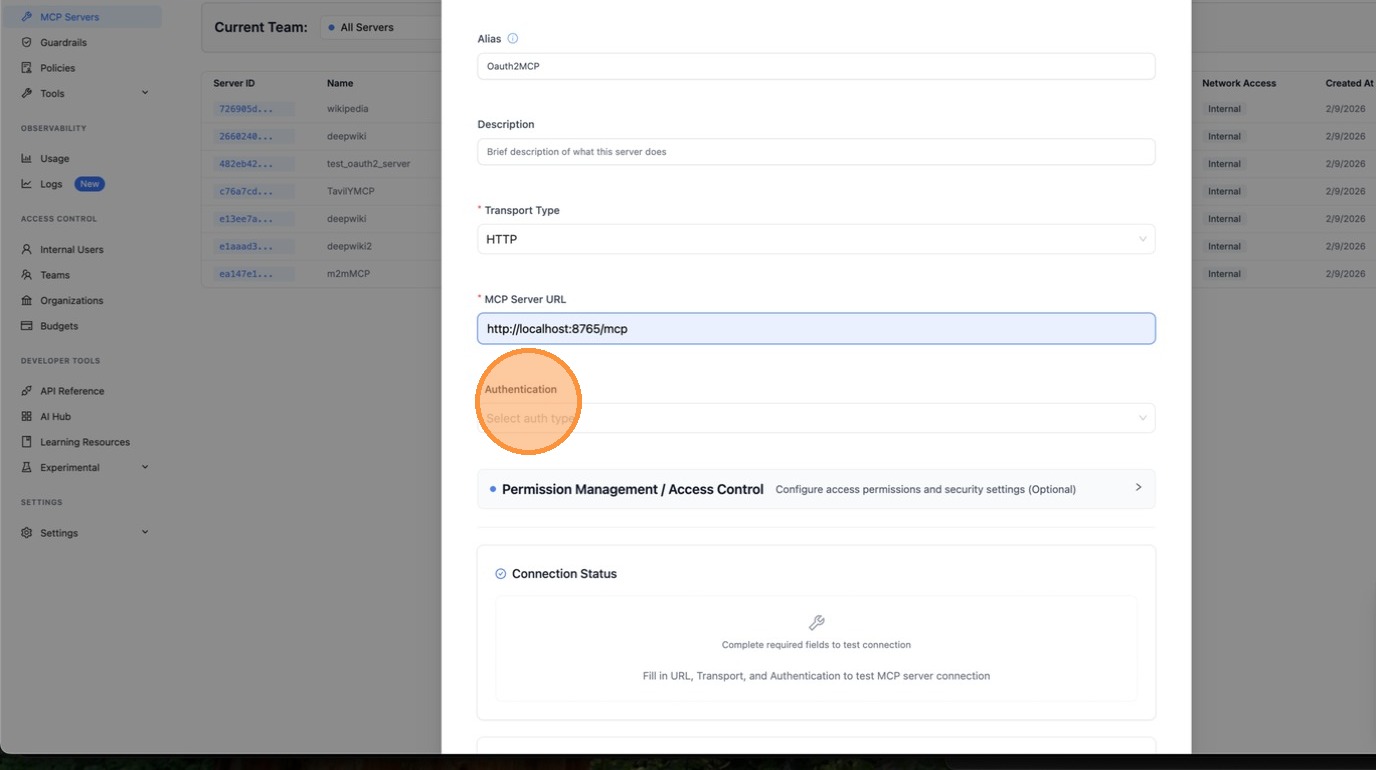
|
||||
|
||||
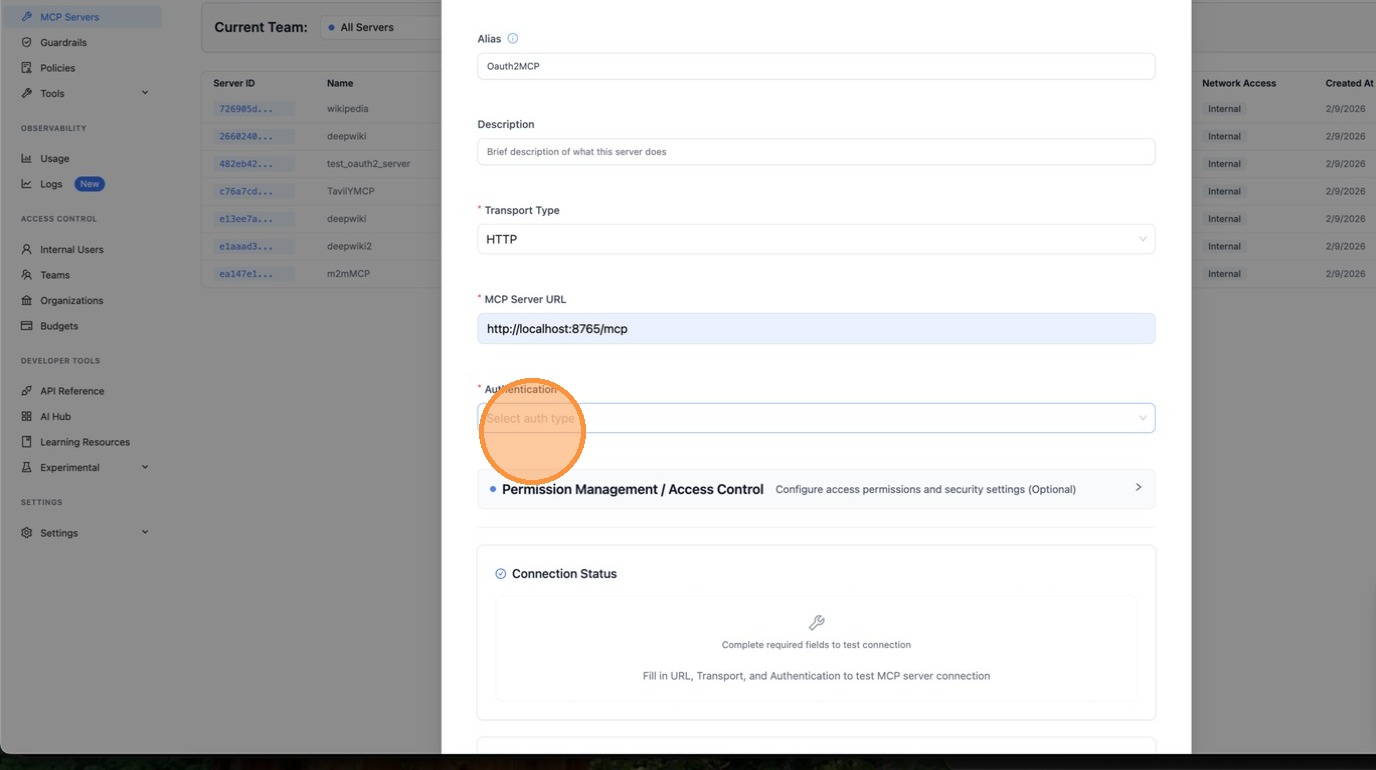
|
||||
|
||||
Choose **Machine-to-Machine (M2M)** as the OAuth flow type. This is for server-to-server authentication using the `client_credentials` grant — no browser interaction required.
|
||||
|
||||
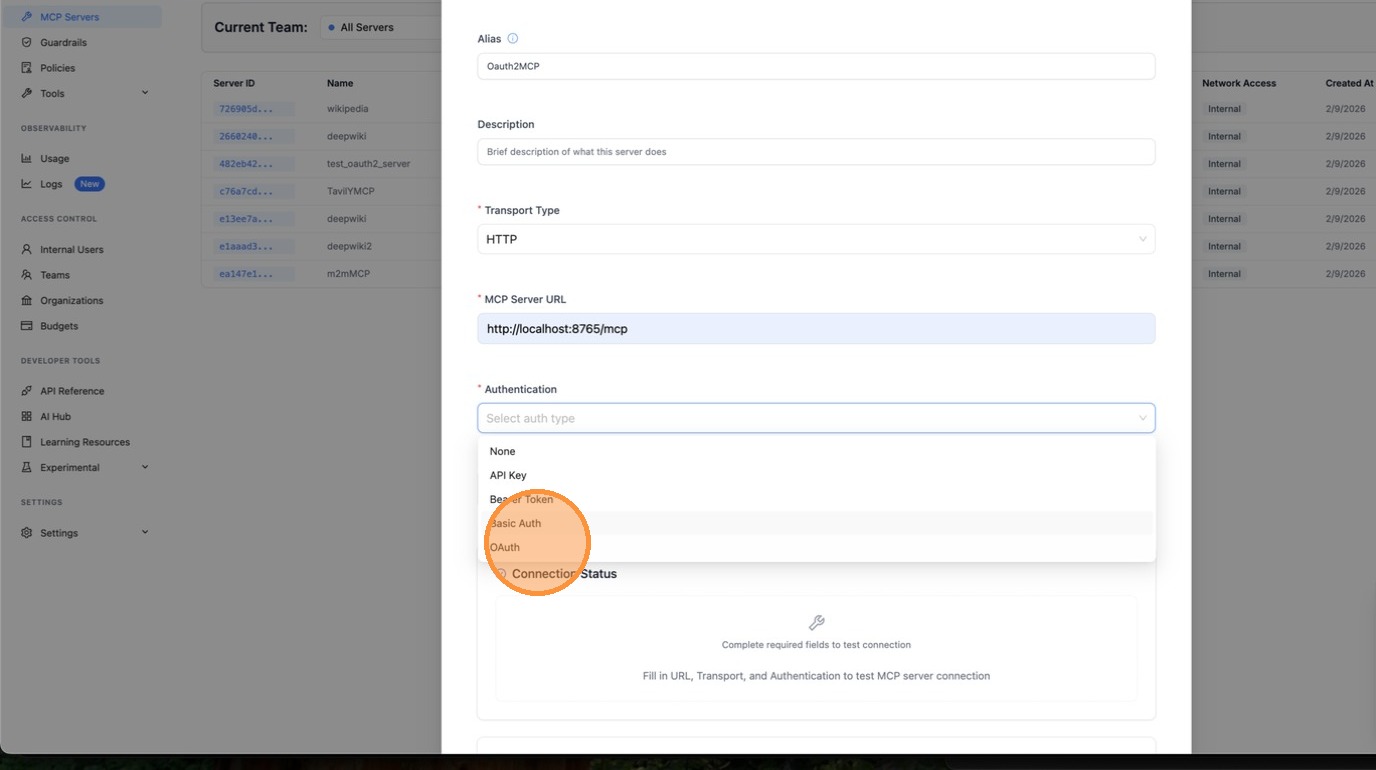
|
||||
|
||||
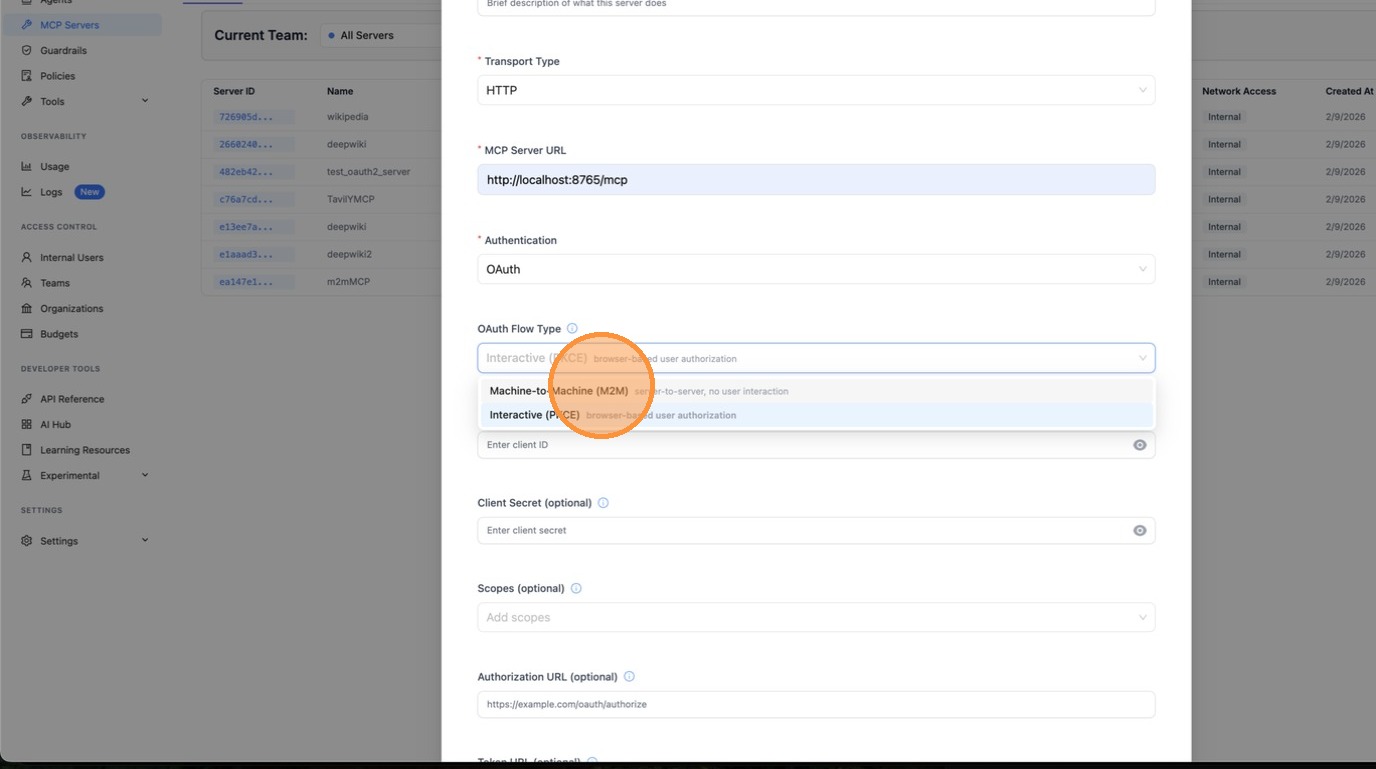
|
||||
|
||||
Fill in the **Client ID** and **Client Secret** provided by your OAuth provider.
|
||||
|
||||
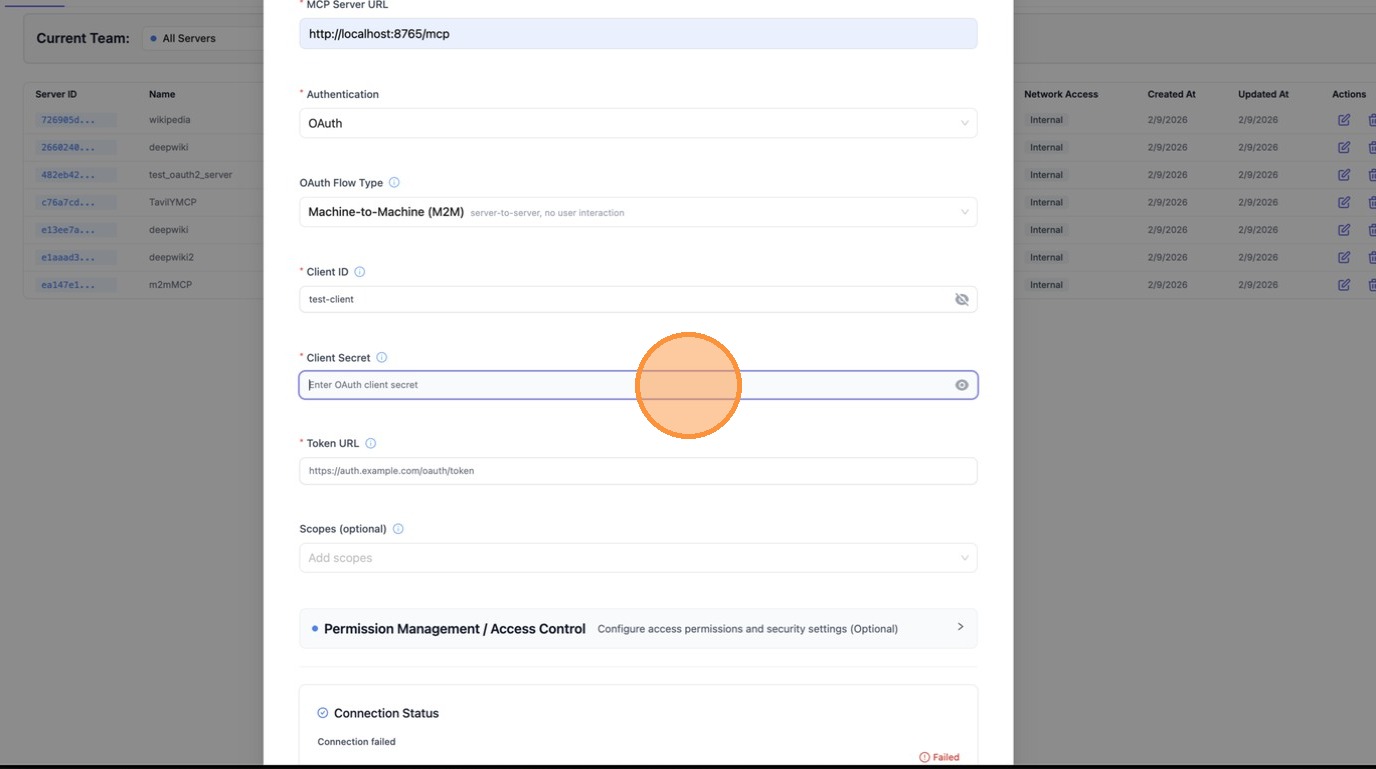
|
||||
|
||||
Enter the **Token URL** — this is the endpoint LiteLLM will call to fetch access tokens using `client_credentials`.
|
||||
|
||||
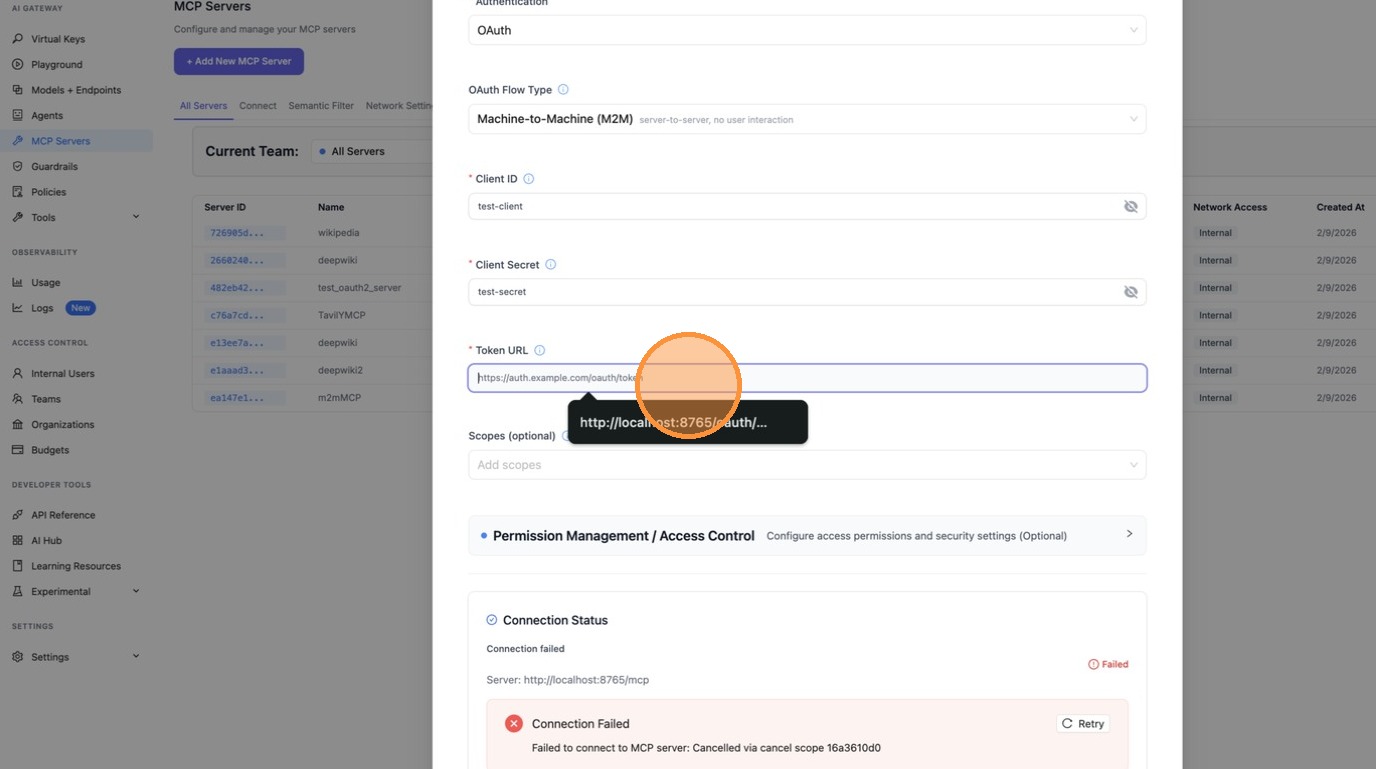
|
||||
|
||||
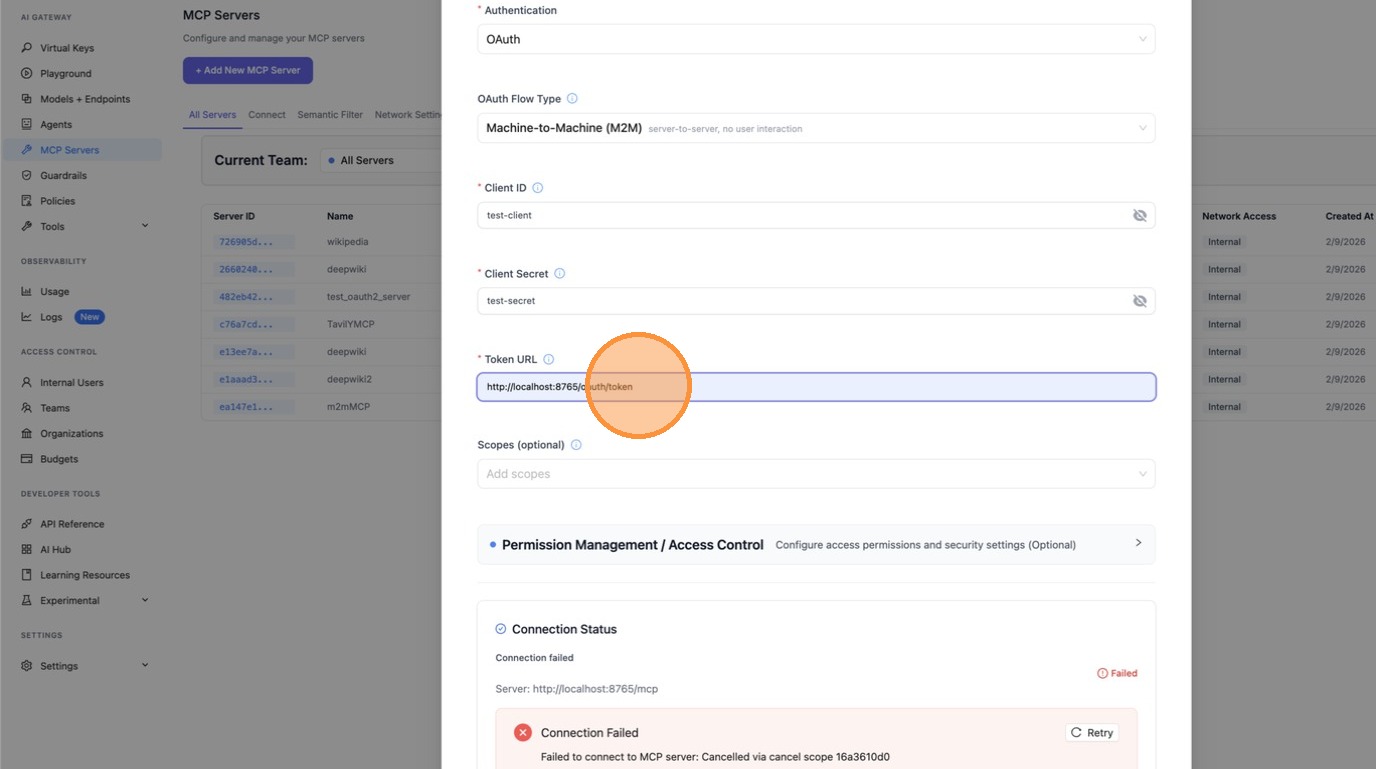
|
||||
|
||||
Scroll down and review the server URL and all fields, then click **Create MCP Server**.
|
||||
|
||||
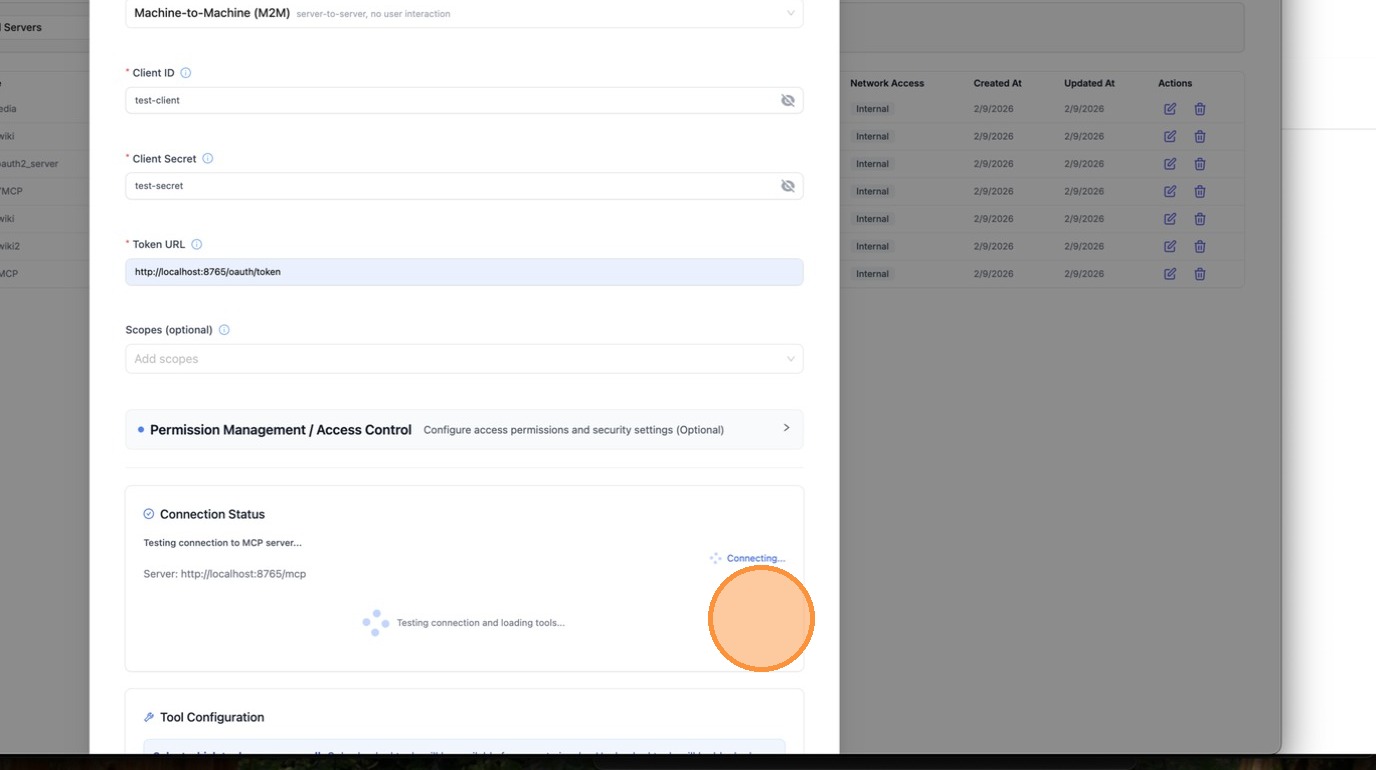
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Once created, open the server and navigate to the **MCP Tools** tab to verify that LiteLLM can connect and list available tools.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Select a tool (e.g. **echo**) to test it. Fill in the required parameters and click **Call Tool**.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
LiteLLM automatically fetches an OAuth token behind the scenes and calls the tool. The result confirms the M2M OAuth flow is working end-to-end.
|
||||
|
||||
|
||||
|
||||
### Config.yaml Setup
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
mcp_servers:
|
||||
my_mcp_server:
|
||||
url: "https://my-mcp-server.com/mcp"
|
||||
auth_type: oauth2
|
||||
client_id: os.environ/MCP_CLIENT_ID
|
||||
client_secret: os.environ/MCP_CLIENT_SECRET
|
||||
token_url: "https://auth.example.com/oauth/token"
|
||||
scopes: ["mcp:read", "mcp:write"] # optional
|
||||
```
|
||||
|
||||
### How It Works
|
||||
|
||||
1. On first MCP request, LiteLLM POSTs to `token_url` with `grant_type=client_credentials`
|
||||
2. The access token is cached in-memory with TTL = `expires_in - 60s`
|
||||
3. Subsequent requests reuse the cached token
|
||||
4. When the token expires, LiteLLM fetches a new one automatically
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant Client as Client
|
||||
participant LiteLLM as LiteLLM Proxy
|
||||
participant Auth as Authorization Server
|
||||
participant MCP as MCP Server
|
||||
|
||||
Client->>LiteLLM: MCP request + LiteLLM API key
|
||||
LiteLLM->>Auth: POST /oauth/token (client_credentials)
|
||||
Auth->>LiteLLM: access_token (expires_in: 3600)
|
||||
LiteLLM->>MCP: MCP request + Bearer token
|
||||
MCP-->>LiteLLM: MCP response
|
||||
LiteLLM-->>Client: MCP response
|
||||
|
||||
Note over LiteLLM: Token cached for subsequent requests
|
||||
Client->>LiteLLM: Next MCP request
|
||||
LiteLLM->>MCP: MCP request + cached Bearer token
|
||||
MCP-->>LiteLLM: MCP response
|
||||
LiteLLM-->>Client: MCP response
|
||||
```
|
||||
|
||||
### Test with Mock Server
|
||||
|
||||
Use [BerriAI/mock-oauth2-mcp-server](https://github.com/BerriAI/mock-oauth2-mcp-server) to test locally:
|
||||
|
||||
```bash title="Terminal 1 - Start mock server" showLineNumbers
|
||||
pip install fastapi uvicorn
|
||||
python mock_oauth2_mcp_server.py # starts on :8765
|
||||
```
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
mcp_servers:
|
||||
test_oauth2:
|
||||
url: "http://localhost:8765/mcp"
|
||||
auth_type: oauth2
|
||||
client_id: "test-client"
|
||||
client_secret: "test-secret"
|
||||
token_url: "http://localhost:8765/oauth/token"
|
||||
```
|
||||
|
||||
```bash title="Terminal 2 - Start proxy and test" showLineNumbers
|
||||
litellm --config config.yaml --port 4000
|
||||
|
||||
# List tools
|
||||
curl http://localhost:4000/mcp-rest/tools/list \
|
||||
-H "Authorization: Bearer sk-1234"
|
||||
|
||||
# Call a tool
|
||||
curl http://localhost:4000/mcp-rest/tools/call \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{"name": "echo", "arguments": {"message": "hello"}}'
|
||||
```
|
||||
|
||||
### Config Reference
|
||||
|
||||
| Field | Required | Description |
|
||||
|-------|----------|-------------|
|
||||
| `auth_type` | Yes | Must be `oauth2` |
|
||||
| `client_id` | Yes | OAuth2 client ID. Supports `os.environ/VAR_NAME` |
|
||||
| `client_secret` | Yes | OAuth2 client secret. Supports `os.environ/VAR_NAME` |
|
||||
| `token_url` | Yes | Token endpoint URL |
|
||||
| `scopes` | No | List of scopes to request |
|
||||
|
||||
## Debugging OAuth
|
||||
|
||||
When the LiteLLM proxy is hosted remotely and you cannot access server logs, enable **debug headers** to get masked authentication diagnostics in the HTTP response.
|
||||
|
||||
### Enable Debug Mode
|
||||
|
||||
Add the `x-litellm-mcp-debug: true` header to your MCP client request.
|
||||
|
||||
**Claude Code:**
|
||||
|
||||
```bash
|
||||
claude mcp add --transport http litellm_proxy http://proxy.example.com/atlassian_mcp/mcp \
|
||||
--header "x-litellm-api-key: Bearer sk-..." \
|
||||
--header "x-litellm-mcp-debug: true"
|
||||
```
|
||||
|
||||
**curl:**
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/atlassian_mcp/mcp \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "x-litellm-api-key: Bearer sk-..." \
|
||||
-H "x-litellm-mcp-debug: true" \
|
||||
-d '{"jsonrpc":"2.0","id":1,"method":"tools/list","params":{}}'
|
||||
```
|
||||
|
||||
### Reading the Debug Response Headers
|
||||
|
||||
The response includes these headers (all sensitive values are masked):
|
||||
|
||||
| Header | Description |
|
||||
|--------|-------------|
|
||||
| `x-mcp-debug-inbound-auth` | Which inbound auth headers were present. |
|
||||
| `x-mcp-debug-oauth2-token` | The OAuth2 token (masked). Shows `SAME_AS_LITELLM_KEY` if the LiteLLM key is leaking. |
|
||||
| `x-mcp-debug-auth-resolution` | Which auth method was used: `oauth2-passthrough`, `m2m-client-credentials`, `per-request-header`, `static-token`, or `no-auth`. |
|
||||
| `x-mcp-debug-outbound-url` | The upstream MCP server URL. |
|
||||
| `x-mcp-debug-server-auth-type` | The `auth_type` configured on the server. |
|
||||
|
||||
**Example — healthy OAuth2 passthrough:**
|
||||
|
||||
```
|
||||
x-mcp-debug-inbound-auth: x-litellm-api-key=Bearer****1234; authorization=Bearer****ef01
|
||||
x-mcp-debug-oauth2-token: Bearer****ef01
|
||||
x-mcp-debug-auth-resolution: oauth2-passthrough
|
||||
x-mcp-debug-outbound-url: https://mcp.atlassian.com/v1/mcp
|
||||
x-mcp-debug-server-auth-type: oauth2
|
||||
```
|
||||
|
||||
**Example — LiteLLM key leaking (misconfigured):**
|
||||
|
||||
```
|
||||
x-mcp-debug-inbound-auth: authorization=Bearer****1234
|
||||
x-mcp-debug-oauth2-token: Bearer****1234 (SAME_AS_LITELLM_KEY - likely misconfigured)
|
||||
x-mcp-debug-auth-resolution: oauth2-passthrough
|
||||
x-mcp-debug-outbound-url: https://mcp.atlassian.com/v1/mcp
|
||||
x-mcp-debug-server-auth-type: oauth2
|
||||
```
|
||||
|
||||
### Common Issues
|
||||
|
||||
#### LiteLLM API key leaking to the MCP server
|
||||
|
||||
**Symptom:** `x-mcp-debug-oauth2-token` shows `SAME_AS_LITELLM_KEY`.
|
||||
|
||||
The `Authorization` header carries the LiteLLM API key instead of an OAuth2 token. The OAuth2 flow never ran because the client already had an `Authorization` header set.
|
||||
|
||||
**Fix:** Move the LiteLLM key to `x-litellm-api-key`:
|
||||
|
||||
```bash
|
||||
# WRONG — blocks OAuth2 discovery
|
||||
claude mcp add --transport http my_server http://proxy/mcp/server \
|
||||
--header "Authorization: Bearer sk-..."
|
||||
|
||||
# CORRECT — LiteLLM key in dedicated header, Authorization free for OAuth2
|
||||
claude mcp add --transport http my_server http://proxy/mcp/server \
|
||||
--header "x-litellm-api-key: Bearer sk-..."
|
||||
```
|
||||
|
||||
#### No OAuth2 token present
|
||||
|
||||
**Symptom:** `x-mcp-debug-oauth2-token` shows `(none)` and `x-mcp-debug-auth-resolution` shows `no-auth`.
|
||||
|
||||
Check that:
|
||||
1. The `Authorization` header is NOT set as a static header in the client config.
|
||||
2. The MCP server in LiteLLM config has `auth_type: oauth2`.
|
||||
3. The `.well-known/oauth-protected-resource` endpoint returns valid metadata.
|
||||
|
||||
#### M2M token used instead of user token
|
||||
|
||||
**Symptom:** `x-mcp-debug-auth-resolution` shows `m2m-client-credentials`.
|
||||
|
||||
The server has `client_id`/`client_secret`/`token_url` configured so LiteLLM is fetching a machine-to-machine token instead of using the per-user OAuth2 token. To use per-user tokens, remove the client credentials from the server config.
|
||||
251
docs/my-website/docs/mcp_public_internet.md
Normal file
|
|
@ -0,0 +1,251 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Exposing MCPs on the Public Internet
|
||||
|
||||
Control which MCP servers are visible to external callers (e.g., ChatGPT, Claude Desktop) vs. internal-only callers. This is useful when you want a subset of your MCP servers available publicly while keeping sensitive servers restricted to your private network.
|
||||
|
||||
## Overview
|
||||
|
||||
| Property | Details |
|
||||
|-------|-------|
|
||||
| Description | IP-based access control for MCP servers — external callers only see servers marked as public |
|
||||
| Setting | `available_on_public_internet` on each MCP server |
|
||||
| Network Config | `mcp_internal_ip_ranges` in `general_settings` |
|
||||
| Supported Clients | ChatGPT, Claude Desktop, Cursor, OpenAI API, or any MCP client |
|
||||
|
||||
## How It Works
|
||||
|
||||
When a request arrives at LiteLLM's MCP endpoints, LiteLLM checks the caller's IP address to determine whether they are an **internal** or **external** caller:
|
||||
|
||||
1. **Extract the client IP** from the incoming request (supports `X-Forwarded-For` when configured behind a reverse proxy).
|
||||
2. **Classify the IP** as internal or external by checking it against the configured private IP ranges (defaults to RFC 1918: `10.0.0.0/8`, `172.16.0.0/12`, `192.168.0.0/16`, `127.0.0.0/8`).
|
||||
3. **Filter the server list**:
|
||||
- **Internal callers** see all MCP servers (public and private).
|
||||
- **External callers** only see servers with `available_on_public_internet: true`.
|
||||
|
||||
This filtering is applied at every MCP access point: the MCP registry, tool listing, tool calling, dynamic server routes, and OAuth discovery endpoints.
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
A[Incoming MCP Request] --> B[Extract Client IP Address]
|
||||
B --> C{Is IP in private ranges?}
|
||||
C -->|Yes - Internal caller| D[Return ALL MCP servers]
|
||||
C -->|No - External caller| E[Return ONLY servers with<br/>available_on_public_internet = true]
|
||||
```
|
||||
|
||||
## Walkthrough
|
||||
|
||||
This walkthrough covers two flows:
|
||||
1. **Adding a public MCP server** (DeepWiki) and connecting to it from ChatGPT
|
||||
2. **Making an existing server private** (Exa) and verifying ChatGPT no longer sees it
|
||||
|
||||
### Flow 1: Add a Public MCP Server (DeepWiki)
|
||||
|
||||
DeepWiki is a free MCP server — a good candidate to expose publicly so AI gateway users can access it from ChatGPT.
|
||||
|
||||
#### Step 1: Create the MCP Server
|
||||
|
||||
Navigate to the MCP Servers page and click **"+ Add New MCP Server"**.
|
||||
|
||||
|
||||
|
||||
The create dialog opens. Enter **"DeepWiki"** as the server name.
|
||||
|
||||
|
||||
|
||||
For the transport type dropdown, select **HTTP** since DeepWiki uses the Streamable HTTP transport.
|
||||
|
||||
|
||||
|
||||
Now scroll down to the MCP Server URL field.
|
||||
|
||||
|
||||
|
||||
Enter the DeepWiki MCP URL: `https://mcp.deepwiki.com/mcp`.
|
||||
|
||||
|
||||
|
||||
With the name, transport, and URL filled in, the basic server configuration is complete.
|
||||
|
||||
|
||||
|
||||
#### Step 2: Enable "Available on Public Internet"
|
||||
|
||||
Before creating, scroll down and expand the **Permission Management / Access Control** section. This is where you control who can see this server.
|
||||
|
||||
|
||||
|
||||
Toggle **"Available on Public Internet"** on. This is the key setting — it tells LiteLLM that external callers (like ChatGPT connecting from the public internet) should be able to discover and use this server.
|
||||
|
||||
|
||||
|
||||
With the toggle enabled, click **"Create"** to save the server.
|
||||
|
||||
|
||||
|
||||
#### Step 3: Connect from ChatGPT
|
||||
|
||||
Now let's verify it works. Open ChatGPT and look for the MCP server icon to add a new connection. The endpoint to use is `<your-litellm-url>/mcp`.
|
||||
|
||||
|
||||
|
||||
In the dropdown, select **"Add an MCP server"** to configure a new connection.
|
||||
|
||||
|
||||
|
||||
ChatGPT asks for a server label. Give it a recognizable name like "LiteLLM".
|
||||
|
||||
|
||||
|
||||
Next, enter the Server URL. This should be your LiteLLM proxy's MCP endpoint — `<your-litellm-url>/mcp`.
|
||||
|
||||
|
||||
|
||||
Paste your LiteLLM URL and confirm it looks correct.
|
||||
|
||||
|
||||
|
||||
ChatGPT also needs authentication. Enter your LiteLLM API key in the authentication field so it can connect to the proxy.
|
||||
|
||||
|
||||
|
||||
Click **"Connect"** to establish the connection.
|
||||
|
||||
|
||||
|
||||
ChatGPT connects and shows the available tools. Since both DeepWiki and Exa are currently marked as public, ChatGPT can see tools from both servers.
|
||||
|
||||
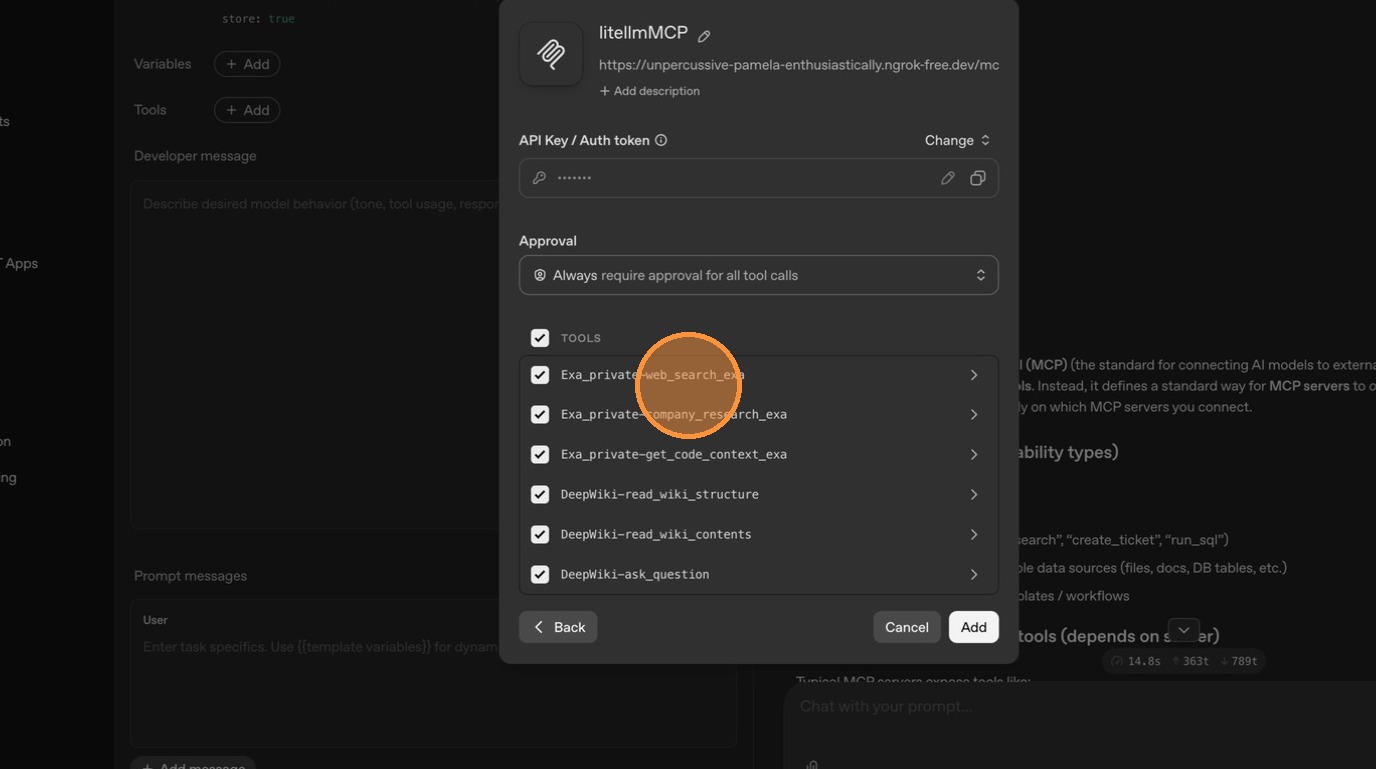
|
||||
|
||||
---
|
||||
|
||||
### Flow 2: Make an Existing Server Private (Exa)
|
||||
|
||||
Now let's do the reverse — take an existing MCP server (Exa) that's currently public and restrict it to internal access only. After this change, ChatGPT should no longer see Exa's tools.
|
||||
|
||||
#### Step 1: Edit the Server
|
||||
|
||||
Go to the MCP Servers table and click on the Exa server to open its detail view.
|
||||
|
||||
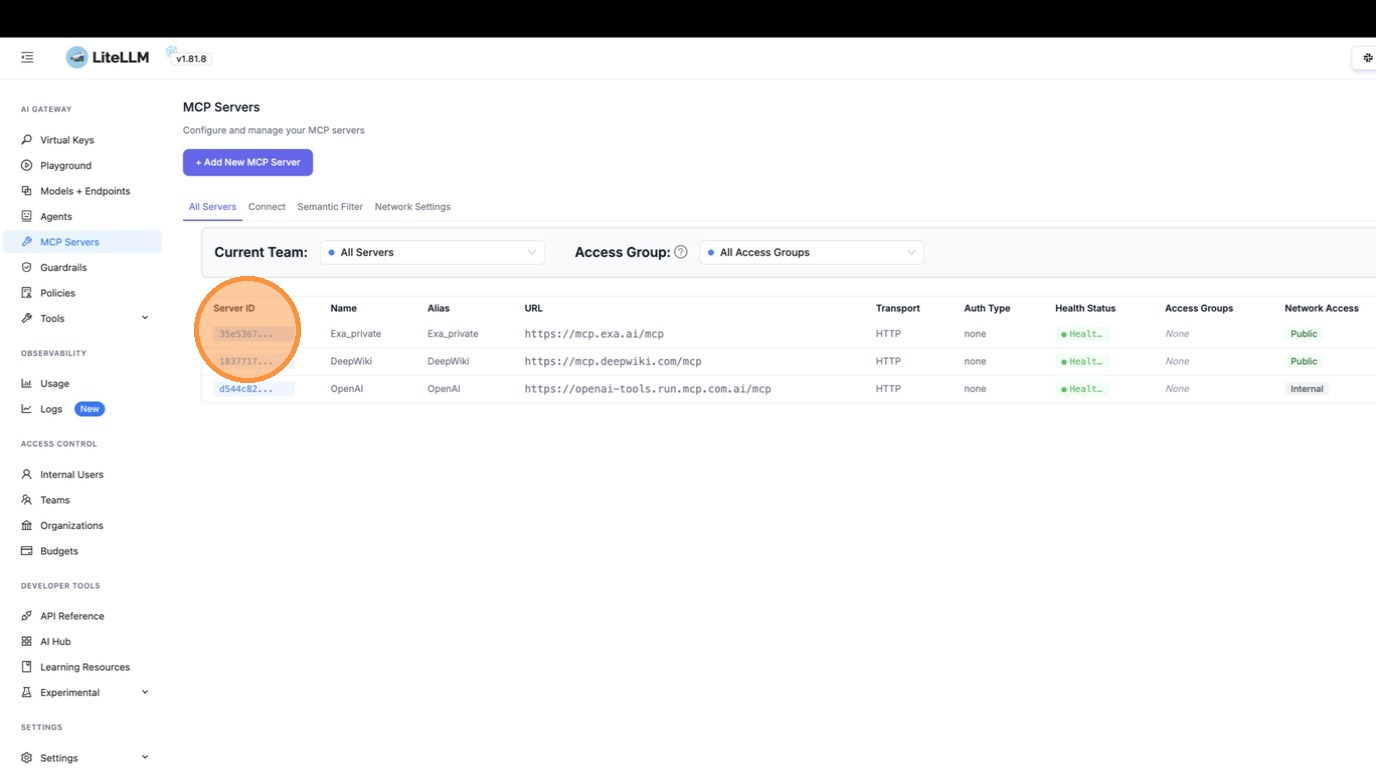
|
||||
|
||||
Switch to the **"Settings"** tab to access the edit form.
|
||||
|
||||
|
||||
|
||||
The edit form loads with Exa's current configuration.
|
||||
|
||||
|
||||
|
||||
#### Step 2: Toggle Off "Available on Public Internet"
|
||||
|
||||
Scroll down and expand the **Permission Management / Access Control** section to find the public internet toggle.
|
||||
|
||||
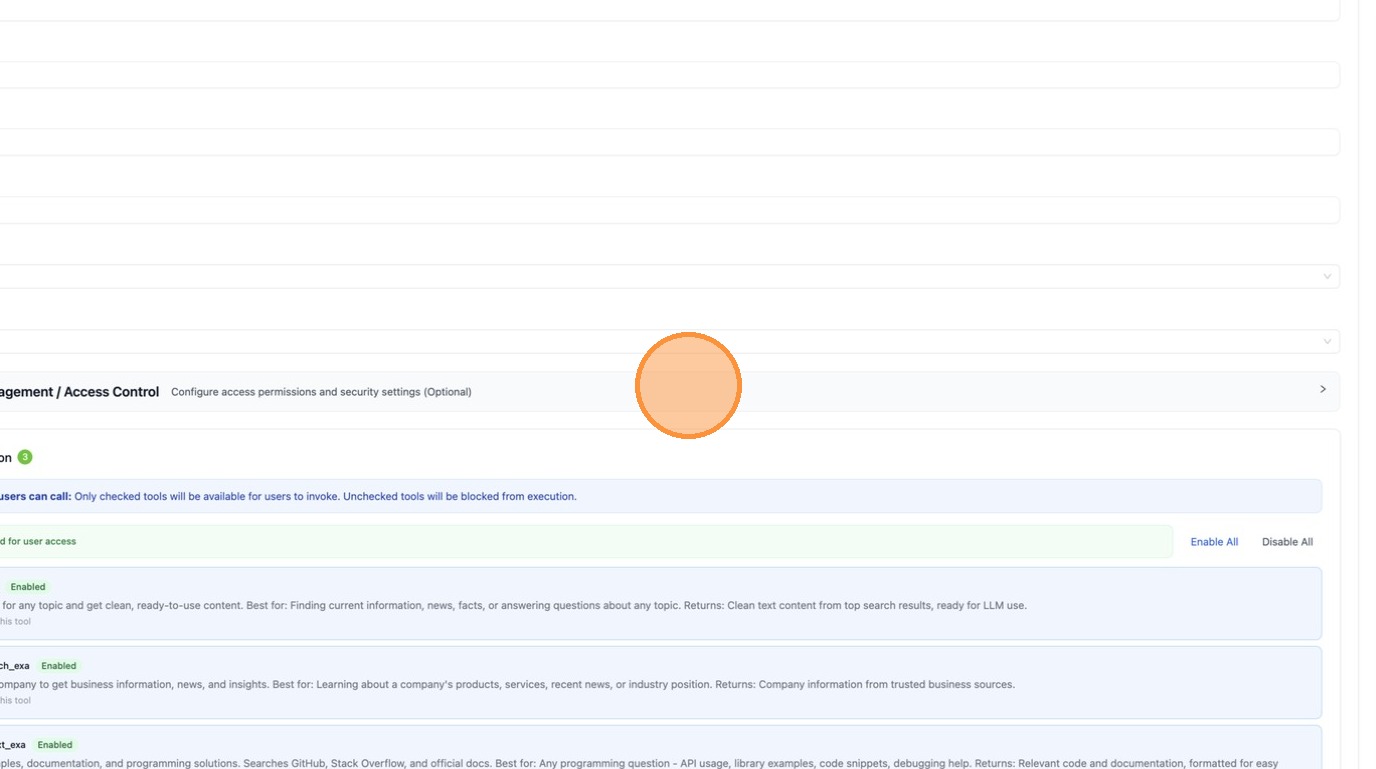
|
||||
|
||||
Toggle **"Available on Public Internet"** off. This will hide Exa from any caller outside your private network.
|
||||
|
||||
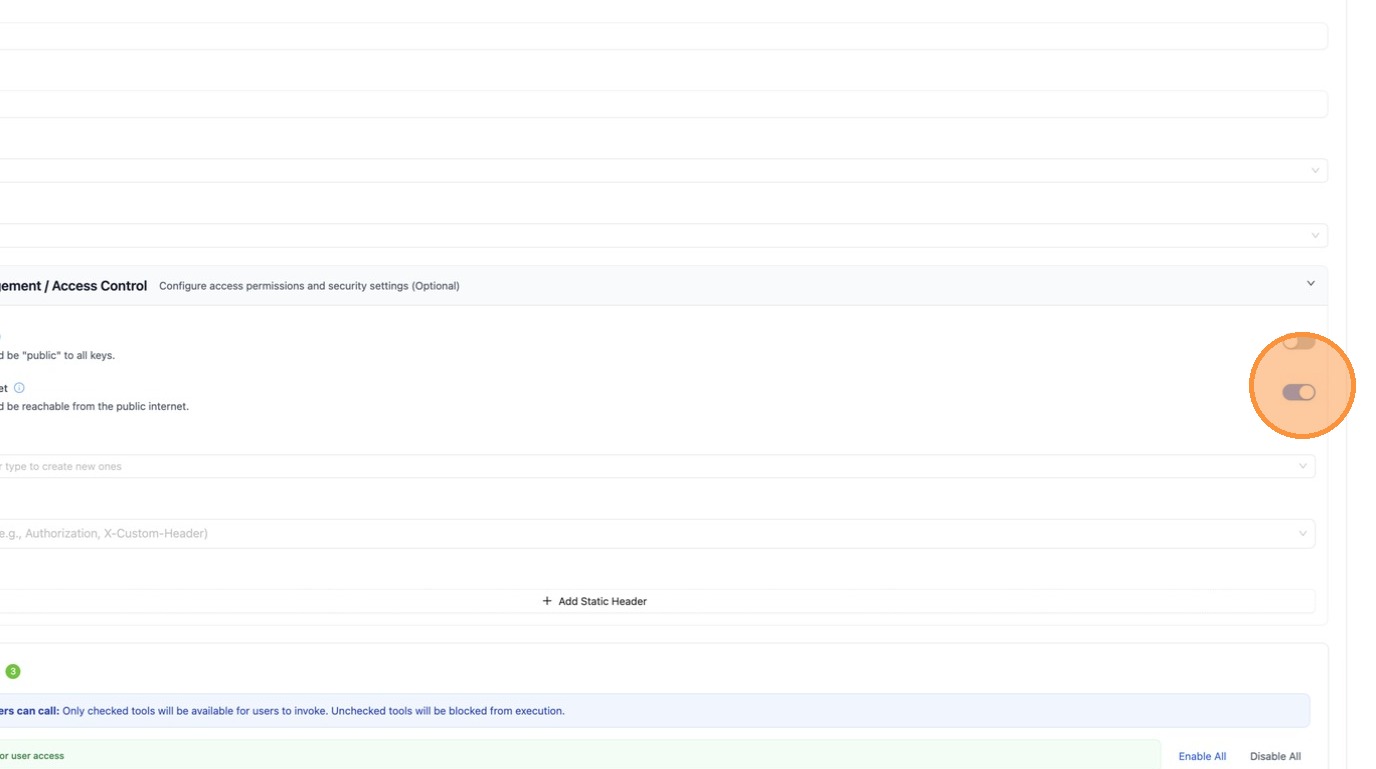
|
||||
|
||||
Click **"Save Changes"** to apply. The change takes effect immediately — no proxy restart needed.
|
||||
|
||||
|
||||
|
||||
#### Step 3: Verify in ChatGPT
|
||||
|
||||
Go back to ChatGPT to confirm Exa is no longer visible. You'll need to reconnect for ChatGPT to re-fetch the tool list.
|
||||
|
||||
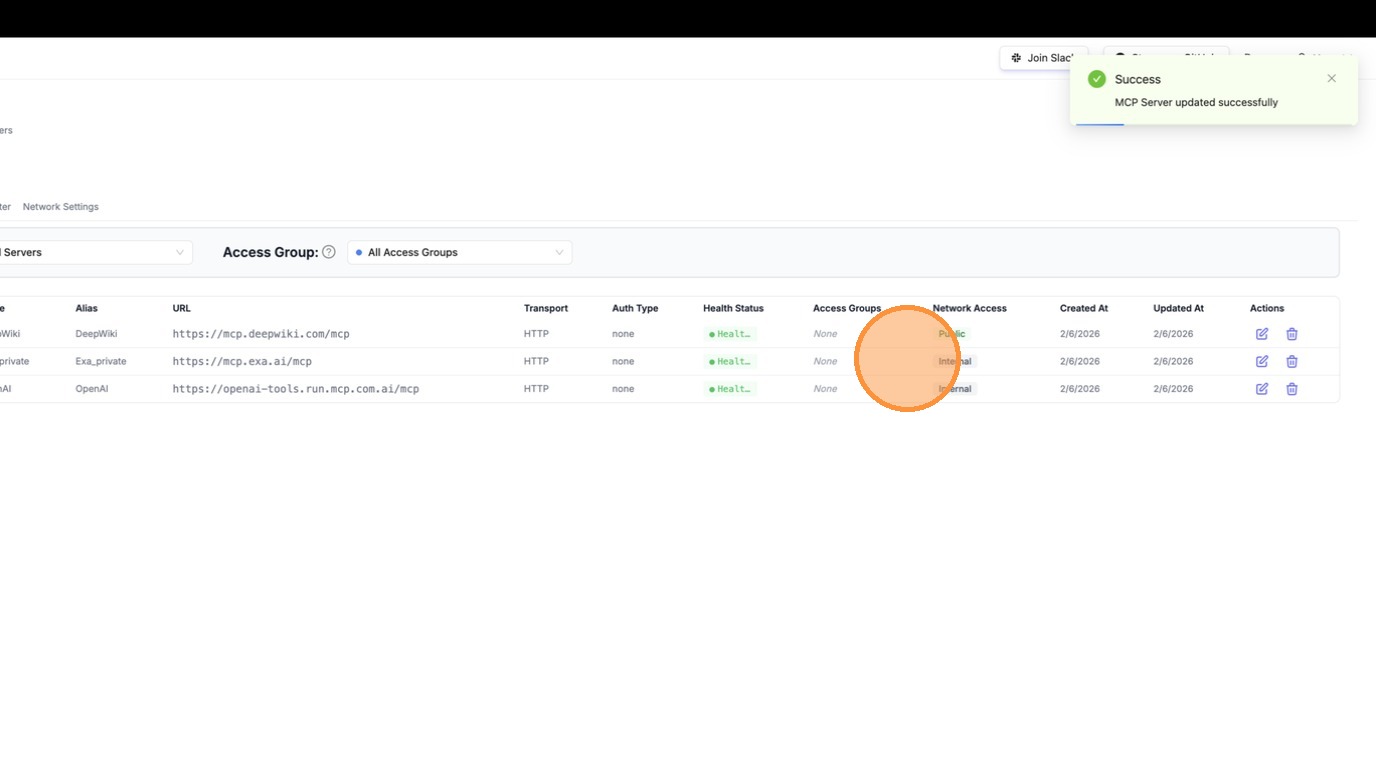
|
||||
|
||||
Open the MCP server settings and select to add or reconnect a server.
|
||||
|
||||
|
||||
|
||||
Enter the same LiteLLM MCP URL as before.
|
||||
|
||||
|
||||
|
||||
Set the server label.
|
||||
|
||||
|
||||
|
||||
Enter your API key for authentication.
|
||||
|
||||
|
||||
|
||||
Click **"Connect"** to re-establish the connection.
|
||||
|
||||
|
||||
|
||||
This time, only DeepWiki's tools appear — Exa is gone. LiteLLM detected that ChatGPT is calling from a public IP and filtered out Exa since it's no longer marked as public. Internal users on your private network would still see both servers.
|
||||
|
||||
|
||||
|
||||
## Configuration Reference
|
||||
|
||||
### Per-Server Setting
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI">
|
||||
|
||||
Toggle **"Available on Public Internet"** in the Permission Management section when creating or editing an MCP server.
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="config" label="config.yaml">
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
mcp_servers:
|
||||
deepwiki:
|
||||
url: https://mcp.deepwiki.com/mcp
|
||||
available_on_public_internet: true # visible to external callers
|
||||
|
||||
exa:
|
||||
url: https://exa.ai/mcp
|
||||
auth_type: api_key
|
||||
auth_value: os.environ/EXA_API_KEY
|
||||
available_on_public_internet: false # internal only (default)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
```bash title="Create a public MCP server" showLineNumbers
|
||||
curl -X POST <your-litellm-url>/v1/mcp/server \
|
||||
-H "Authorization: Bearer sk-..." \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"server_name": "DeepWiki",
|
||||
"url": "https://mcp.deepwiki.com/mcp",
|
||||
"transport": "http",
|
||||
"available_on_public_internet": true
|
||||
}'
|
||||
```
|
||||
|
||||
```bash title="Update an existing server" showLineNumbers
|
||||
curl -X PUT <your-litellm-url>/v1/mcp/server \
|
||||
-H "Authorization: Bearer sk-..." \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"server_id": "<server-id>",
|
||||
"available_on_public_internet": false
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Custom Private IP Ranges
|
||||
|
||||
By default, LiteLLM treats RFC 1918 private ranges as internal. You can customize this in the **Network Settings** tab under MCP Servers, or via config:
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
general_settings:
|
||||
mcp_internal_ip_ranges:
|
||||
- "10.0.0.0/8"
|
||||
- "172.16.0.0/12"
|
||||
- "192.168.0.0/16"
|
||||
- "100.64.0.0/10" # Add your VPN/Tailscale range
|
||||
```
|
||||
|
||||
When empty, the standard private ranges are used (`10.0.0.0/8`, `172.16.0.0/12`, `192.168.0.0/16`, `127.0.0.0/8`).
|
||||
|
|
@ -6,6 +6,39 @@ When LiteLLM acts as an MCP proxy, traffic normally flows `Client → LiteLLM Pr
|
|||
|
||||
For provisioning steps, transport options, and configuration fields, refer to [mcp.md](./mcp.md).
|
||||
|
||||
## Quick Start: Debug with One Command
|
||||
|
||||
The fastest way to debug MCP issues is to enable **debug headers**. Run this curl against your LiteLLM proxy and check the response headers:
|
||||
|
||||
```bash
|
||||
curl -si -X POST http://localhost:4000/{your_mcp_server}/mcp \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "x-litellm-api-key: Bearer sk-YOUR_KEY" \
|
||||
-H "x-litellm-mcp-debug: true" \
|
||||
-d '{"jsonrpc":"2.0","id":1,"method":"tools/list","params":{}}' \
|
||||
2>&1 | grep -i "x-mcp-debug"
|
||||
```
|
||||
|
||||
This returns masked diagnostic headers that tell you exactly what's happening with authentication:
|
||||
|
||||
```
|
||||
x-mcp-debug-inbound-auth: x-litellm-api-key=Bearer****1234
|
||||
x-mcp-debug-oauth2-token: Bearer****ef01
|
||||
x-mcp-debug-auth-resolution: oauth2-passthrough
|
||||
x-mcp-debug-outbound-url: https://mcp.atlassian.com/v1/mcp
|
||||
x-mcp-debug-server-auth-type: oauth2
|
||||
```
|
||||
|
||||
If you see `SAME_AS_LITELLM_KEY` in `x-mcp-debug-oauth2-token`, your LiteLLM API key is leaking to the MCP server instead of an OAuth2 token. See [Debugging OAuth](./mcp_oauth#debugging-oauth) for the fix and other common issues.
|
||||
|
||||
For Claude Code, add the debug header to your MCP config:
|
||||
|
||||
```bash
|
||||
claude mcp add --transport http my_server http://localhost:4000/my_mcp/mcp \
|
||||
--header "x-litellm-api-key: Bearer sk-..." \
|
||||
--header "x-litellm-mcp-debug: true"
|
||||
```
|
||||
|
||||
## Locate the Error Source
|
||||
|
||||
Pin down where the failure occurs before adjusting settings so you do not mix symptoms from separate hops.
|
||||
|
|
@ -13,7 +46,7 @@ Pin down where the failure occurs before adjusting settings so you do not mix sy
|
|||
### LiteLLM UI / Playground Errors (LiteLLM → MCP)
|
||||
Failures shown on the MCP creation form or within the MCP Tool Testing Playground mean the LiteLLM proxy cannot reach the MCP server. Typical causes are misconfiguration (transport, headers, credentials), MCP/server outages, network/firewall blocks, or inaccessible OAuth metadata.
|
||||
|
||||
<Image
|
||||
<Image
|
||||
img={require('../img/mcp_tool_testing_playground.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0'}}
|
||||
/>
|
||||
|
|
@ -22,7 +55,7 @@ Failures shown on the MCP creation form or within the MCP Tool Testing Playgroun
|
|||
|
||||
**Actions**
|
||||
- Capture LiteLLM proxy logs alongside MCP-server logs (see [Error Log Example](./mcp_troubleshoot#error-log-example-failed-mcp-call)) to inspect the request/response pair and stack traces.
|
||||
- From the LiteLLM server, run Method 2 ([`curl` smoke test](./mcp_troubleshoot#curl-smoke-test)) against the MCP endpoint to confirm basic connectivity.
|
||||
- From the LiteLLM server, run a [`curl` smoke test](./mcp_troubleshoot#curl-smoke-test) against the MCP endpoint to confirm basic connectivity.
|
||||
|
||||
### Client Traffic Issues (Client → LiteLLM)
|
||||
If only real client requests fail, determine whether LiteLLM ever reaches the MCP hop.
|
||||
|
|
@ -43,7 +76,7 @@ During `/responses` or `/chat/completions`, LiteLLM may trigger MCP tool calls m
|
|||
- Validate MCP connectivity with the [MCP Inspector](./mcp_troubleshoot#mcp-inspector) to ensure the server responds.
|
||||
- Reproduce the same MCP call via the LiteLLM Playground to confirm LiteLLM can complete the MCP hop independently.
|
||||
|
||||
<Image
|
||||
<Image
|
||||
img={require('../img/mcp_playground.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0'}}
|
||||
/>
|
||||
|
|
@ -55,6 +88,10 @@ LiteLLM performs metadata discovery per the MCP spec ([section 2.3](https://mode
|
|||
- Use `curl <metadata_url>` (or similar) from the LiteLLM host to ensure the discovery document is reachable and contains the expected authorization/token endpoints.
|
||||
- Record the exact metadata URL, requested scopes, and any static client credentials so support can replay the discovery step if needed.
|
||||
|
||||
## Debugging OAuth
|
||||
|
||||
For detailed OAuth2 debugging — including debug header reference, common misconfigurations, and example output — see [Debugging OAuth](./mcp_oauth#debugging-oauth).
|
||||
|
||||
## Verify Connectivity
|
||||
|
||||
Run lightweight validations before impacting production traffic.
|
||||
|
|
@ -66,7 +103,7 @@ Use the MCP Inspector when you need to test both `Client → LiteLLM` and `Clien
|
|||
2. Configure and connect:
|
||||
- **Transport Type:** choose the transport the client uses (Streamable HTTP for LiteLLM).
|
||||
- **URL:** the endpoint under test (LiteLLM MCP URL for `Client → LiteLLM`, or the MCP server URL for `Client → MCP`).
|
||||
- **Custom Headers:** e.g., `Authorization: Bearer <LiteLLM API Key>`.
|
||||
- **Custom Headers:** e.g., `x-litellm-api-key: Bearer <LiteLLM API Key>`.
|
||||
3. Open the **Tools** tab and click **List Tools** to verify the MCP alias responds.
|
||||
|
||||
### `curl` Smoke Test
|
||||
|
|
@ -79,7 +116,7 @@ curl -X POST https://your-target-domain.example.com/mcp \
|
|||
-d '{"jsonrpc":"2.0","id":1,"method":"tools/list","params":{}}'
|
||||
```
|
||||
|
||||
Add `-H "Authorization: Bearer <LiteLLM API Key>"` when the target is a LiteLLM endpoint that requires authentication. Adjust the headers, or payload to target other MCP methods. Matching failures between `curl` and LiteLLM confirm that the MCP server or network/OAuth layer is the culprit.
|
||||
Add `-H "x-litellm-api-key: Bearer <LiteLLM API Key>"` when the target is a LiteLLM endpoint that requires authentication. Adjust the headers or payload to target other MCP methods. Matching failures between `curl` and LiteLLM confirm that the MCP server or network/OAuth layer is the culprit.
|
||||
|
||||
## Review Logs
|
||||
|
||||
|
|
|
|||
|
|
@ -215,6 +215,66 @@ The following parameters can be updated on a continuation of a trace by passing
|
|||
|
||||
Any other key value pairs passed into the metadata not listed in the above spec for a `litellm` completion will be added as a metadata key value pair for the generation.
|
||||
|
||||
#### Multiple Langfuse Projects (Per-Request Credentials)
|
||||
|
||||
You can send traces to different Langfuse projects per request by passing credentials directly to `completion()` or `acompletion()`. This works alongside (or instead of) the global env vars and is useful when different teams or business processes use different Langfuse projects.
|
||||
|
||||
Pass **`langfuse_public_key`**, **`langfuse_secret_key`** (or **`langfuse_secret`**), and optionally **`langfuse_host`** as keyword arguments:
|
||||
|
||||
```python
|
||||
import litellm
|
||||
from litellm import completion
|
||||
|
||||
# Optional: set a default via env for requests that don't pass credentials
|
||||
# os.environ["LANGFUSE_PUBLIC_KEY"] = "pk-default..."
|
||||
# os.environ["LANGFUSE_SECRET_KEY"] = "sk-default..."
|
||||
|
||||
litellm.success_callback = ["langfuse"]
|
||||
litellm.failure_callback = ["langfuse"]
|
||||
|
||||
# Request 1 → Langfuse Project A
|
||||
response_a = completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "Hello from team A"}],
|
||||
langfuse_public_key="pk-lf-project-a...",
|
||||
langfuse_secret_key="sk-lf-project-a...",
|
||||
langfuse_host="https://us.cloud.langfuse.com", # optional
|
||||
)
|
||||
|
||||
# Request 2 → Langfuse Project B (different project)
|
||||
response_b = completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "Hello from team B"}],
|
||||
langfuse_public_key="pk-lf-project-b...",
|
||||
langfuse_secret_key="sk-lf-project-b...",
|
||||
langfuse_host="https://eu.cloud.langfuse.com", # optional, can differ per project
|
||||
)
|
||||
```
|
||||
|
||||
Async usage with per-request credentials:
|
||||
|
||||
```python
|
||||
import litellm
|
||||
from litellm import acompletion
|
||||
|
||||
litellm.success_callback = ["langfuse"]
|
||||
litellm.failure_callback = ["langfuse"]
|
||||
|
||||
response = await acompletion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "Hi"}],
|
||||
langfuse_public_key="pk-lf-...",
|
||||
langfuse_secret_key="sk-lf-...",
|
||||
langfuse_host="https://us.cloud.langfuse.com", # optional
|
||||
)
|
||||
```
|
||||
|
||||
- **`langfuse_public_key`** – Langfuse project public key (required for per-request override).
|
||||
- **`langfuse_secret_key`** or **`langfuse_secret`** – Langfuse secret key (either name is accepted).
|
||||
- **`langfuse_host`** – Langfuse host URL (e.g. `https://us.cloud.langfuse.com`); optional, defaults to env or Langfuse cloud.
|
||||
|
||||
When these are passed, that request uses this project (and host) for the Langfuse callback; when omitted, the callback uses the global Langfuse client (from env vars if set). LiteLLM caches a Langfuse client per credential set to avoid creating a new client on every request.
|
||||
|
||||
#### Disable Logging - Specific Calls
|
||||
|
||||
To disable logging for specific calls use the `no-log` flag.
|
||||
|
|
|
|||
|
|
@ -556,3 +556,147 @@ for event in response.get("completion"):
|
|||
|
||||
print(completion)
|
||||
```
|
||||
|
||||
## Using LangChain AWS SDK with LiteLLM
|
||||
|
||||
You can use the [LangChain AWS SDK](https://python.langchain.com/docs/integrations/chat/bedrock/) with LiteLLM Proxy to get cost tracking, load balancing, and other LiteLLM features.
|
||||
|
||||
### Quick Start
|
||||
|
||||
**1. Install LangChain AWS**:
|
||||
|
||||
```bash showLineNumbers
|
||||
pip install langchain-aws
|
||||
```
|
||||
|
||||
**2. Setup LiteLLM Proxy**:
|
||||
|
||||
Create a `config.yaml`:
|
||||
|
||||
```yaml showLineNumbers
|
||||
model_list:
|
||||
- model_name: claude-sonnet
|
||||
litellm_params:
|
||||
model: bedrock/us.anthropic.claude-3-7-sonnet-20250219-v1:0
|
||||
aws_region_name: us-east-1
|
||||
custom_llm_provider: bedrock
|
||||
```
|
||||
|
||||
Start the proxy:
|
||||
|
||||
```bash showLineNumbers
|
||||
export AWS_ACCESS_KEY_ID="your-access-key"
|
||||
export AWS_SECRET_ACCESS_KEY="your-secret-key"
|
||||
|
||||
litellm --config config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
**3. Use LangChain with LiteLLM**:
|
||||
|
||||
```python showLineNumbers
|
||||
from langchain_aws import ChatBedrockConverse
|
||||
from langchain_core.messages import HumanMessage
|
||||
|
||||
# Your LiteLLM API key
|
||||
API_KEY = "Bearer sk-1234"
|
||||
|
||||
# Initialize ChatBedrockConverse pointing to LiteLLM proxy
|
||||
llm = ChatBedrockConverse(
|
||||
model_id="us.anthropic.claude-3-7-sonnet-20250219-v1:0",
|
||||
endpoint_url="http://localhost:4000/bedrock",
|
||||
region_name="us-east-1",
|
||||
aws_access_key_id=API_KEY,
|
||||
aws_secret_access_key="bedrock" # Any non-empty value works
|
||||
)
|
||||
|
||||
# Invoke the model
|
||||
messages = [HumanMessage(content="Hello, how are you?")]
|
||||
response = llm.invoke(messages)
|
||||
|
||||
print(response.content)
|
||||
```
|
||||
|
||||
### Advanced Example: PDF Document Processing with Citations
|
||||
|
||||
LangChain AWS SDK supports Bedrock's document processing features. Here's how to use it with LiteLLM:
|
||||
|
||||
```python showLineNumbers
|
||||
import os
|
||||
import json
|
||||
from langchain_aws import ChatBedrockConverse
|
||||
from langchain_core.messages import HumanMessage
|
||||
|
||||
# Your LiteLLM API key
|
||||
API_KEY = "Bearer sk-1234"
|
||||
|
||||
def get_llm() -> ChatBedrockConverse:
|
||||
"""Initialize LLM pointing to LiteLLM proxy"""
|
||||
llm = ChatBedrockConverse(
|
||||
model_id="us.anthropic.claude-3-7-sonnet-20250219-v1:0",
|
||||
base_model_id="anthropic.claude-3-7-sonnet-20250219-v1:0",
|
||||
endpoint_url="http://localhost:4000/bedrock",
|
||||
region_name="us-east-1",
|
||||
aws_access_key_id=API_KEY,
|
||||
aws_secret_access_key="bedrock"
|
||||
)
|
||||
return llm
|
||||
|
||||
if __name__ == "__main__":
|
||||
# Initialize the LLM
|
||||
llm = get_llm()
|
||||
|
||||
# Read PDF file as bytes (Converse API requires raw bytes)
|
||||
with open("your-document.pdf", "rb") as file:
|
||||
file_bytes = file.read()
|
||||
|
||||
# Prepare messages with document attachment
|
||||
messages = [
|
||||
HumanMessage(content=[
|
||||
{"text": "What is the policy number in this document?"},
|
||||
{
|
||||
"document": {
|
||||
"format": "pdf",
|
||||
"name": "PolicyDocument",
|
||||
"source": {"bytes": file_bytes},
|
||||
"citations": {"enabled": True}
|
||||
}
|
||||
}
|
||||
])
|
||||
]
|
||||
|
||||
# Invoke the LLM
|
||||
response = llm.invoke(messages)
|
||||
|
||||
# Print response with citations
|
||||
print(json.dumps(response.content, indent=4))
|
||||
```
|
||||
|
||||
### Supported LangChain Features
|
||||
|
||||
All LangChain AWS features work with LiteLLM:
|
||||
|
||||
| Feature | Supported | Notes |
|
||||
|---------|-----------|-------|
|
||||
| Text Generation | ✅ | Full support |
|
||||
| Streaming | ✅ | Use `stream()` method |
|
||||
| Document Processing | ✅ | PDF, images, etc. |
|
||||
| Citations | ✅ | Enable in document config |
|
||||
| Tool Use | ✅ | Function calling support |
|
||||
| Multi-modal | ✅ | Text + images + documents |
|
||||
|
||||
### Troubleshooting
|
||||
|
||||
**Issue**: `UnknownOperationException` error
|
||||
|
||||
**Solution**: Make sure you're using the correct endpoint URL format:
|
||||
- ✅ Correct: `http://localhost:4000/bedrock`
|
||||
- ❌ Wrong: `http://localhost:4000/bedrock/v2`
|
||||
|
||||
**Issue**: Authentication errors
|
||||
|
||||
**Solution**: Ensure your API key is in the correct format:
|
||||
```python
|
||||
aws_access_key_id="Bearer sk-1234" # Include "Bearer " prefix
|
||||
```
|
||||
|
|
|
|||
|
|
@ -1473,6 +1473,20 @@ LiteLLM translates OpenAI's `reasoning_effort` to Anthropic's `thinking` paramet
|
|||
| "medium" | "budget_tokens": 2048 |
|
||||
| "high" | "budget_tokens": 4096 |
|
||||
|
||||
:::note
|
||||
For Claude Opus 4.6, all `reasoning_effort` values (`low`, `medium`, `high`) are mapped to `thinking: {type: "adaptive"}`. To use explicit thinking budgets, pass the native `thinking` parameter directly:
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
resp = completion(
|
||||
model="anthropic/claude-opus-4-6",
|
||||
messages=[{"role": "user", "content": "What is the capital of France?"}],
|
||||
thinking={"type": "enabled", "budget_tokens": 1024},
|
||||
)
|
||||
```
|
||||
:::
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
|
|
@ -1614,8 +1628,65 @@ curl http://0.0.0.0:4000/v1/chat/completions \
|
|||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
#### Adaptive Thinking (Claude Opus 4.6)
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-opus-4-6",
|
||||
messages=[{"role": "user", "content": "What is the optimal strategy for solving this problem?"}],
|
||||
thinking={"type": "adaptive"},
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer $LITELLM_KEY" \
|
||||
-d '{
|
||||
"model": "anthropic/claude-opus-4-6",
|
||||
"messages": [{"role": "user", "content": "What is the optimal strategy for solving this problem?"}],
|
||||
"thinking": {"type": "adaptive"}
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
#### Enabled Thinking with Budget
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-opus-4-6",
|
||||
messages=[{"role": "user", "content": "What is the capital of France?"}],
|
||||
thinking={"type": "enabled", "budget_tokens": 5000},
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer $LITELLM_KEY" \
|
||||
-d '{
|
||||
"model": "anthropic/claude-opus-4-6",
|
||||
"messages": [{"role": "user", "content": "What is the capital of France?"}],
|
||||
"thinking": {"type": "enabled", "budget_tokens": 5000}
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## **Passing Extra Headers to Anthropic API**
|
||||
|
||||
|
|
|
|||
|
|
@ -1,7 +1,7 @@
|
|||
# Dashscope (Qwen API)
|
||||
# Dashscope API (Qwen models)
|
||||
https://dashscope.console.aliyun.com/
|
||||
|
||||
**We support ALL Qwen models, just set `dashscope/` as a prefix when sending completion requests**
|
||||
**We support ALL Qwen models (from Alibaba Cloud), just set `dashscope/` as a prefix when sending completion requests**
|
||||
|
||||
## API Key
|
||||
```python
|
||||
|
|
@ -9,6 +9,26 @@ https://dashscope.console.aliyun.com/
|
|||
os.environ['DASHSCOPE_API_KEY']
|
||||
```
|
||||
|
||||
## API Base
|
||||
You can optionally specify the API base URL depending on your region:
|
||||
|
||||
| Region | API Base |
|
||||
|--------|----------|
|
||||
| **International** | `https://dashscope-intl.aliyuncs.com/compatible-mode/v1` |
|
||||
| **China/Beijing** | `https://dashscope.aliyuncs.com/compatible-mode/v1` |
|
||||
|
||||
```python
|
||||
# Set via environment variable
|
||||
os.environ['DASHSCOPE_API_BASE'] = "https://dashscope-intl.aliyuncs.com/compatible-mode/v1"
|
||||
|
||||
# Or pass directly in the completion call
|
||||
response = completion(
|
||||
model="dashscope/qwen-turbo",
|
||||
messages=[{"role": "user", "content": "hello"}],
|
||||
api_base="https://dashscope-intl.aliyuncs.com/compatible-mode/v1"
|
||||
)
|
||||
```
|
||||
|
||||
## Sample Usage
|
||||
```python
|
||||
from litellm import completion
|
||||
|
|
@ -43,9 +63,7 @@ for chunk in response:
|
|||
```
|
||||
|
||||
|
||||
## Supported Models - ALL Qwen Models Supported!
|
||||
We support ALL Qwen models, just set `dashscope/` as a prefix when sending completion requests
|
||||
|
||||
## All supported Models
|
||||
|
||||
[DashScope Model List](https://help.aliyun.com/zh/model-studio/compatibility-of-openai-with-dashscope?spm=a2c4g.11186623.help-menu-2400256.d_2_8_0.1efd516e2tTXBn&scm=20140722.H_2833609._.OR_help-T_cn~zh-V_1#7f9c78ae99pwz)
|
||||
|
||||
|
|
|
|||
|
|
@ -243,6 +243,13 @@ ElevenLabs provides high-quality text-to-speech capabilities through their TTS A
|
|||
| Supported Operations | `/audio/speech` |
|
||||
| Link to Provider Doc | [ElevenLabs TTS API ↗](https://elevenlabs.io/docs/api-reference/text-to-speech) |
|
||||
|
||||
### Supported Models
|
||||
|
||||
| Model | Route | Description |
|
||||
|-------|-------|-------------|
|
||||
| Eleven v3 | `elevenlabs/eleven_v3` | Most expressive model. 70+ languages, audio tags support for sound effects and pauses. |
|
||||
| Eleven Multilingual v2 | `elevenlabs/eleven_multilingual_v2` | Default TTS model. 29 languages, stable and production-ready. |
|
||||
|
||||
### Quick Start
|
||||
|
||||
#### LiteLLM Python SDK
|
||||
|
|
@ -265,6 +272,26 @@ with open("test_output.mp3", "wb") as f:
|
|||
f.write(audio.read())
|
||||
```
|
||||
|
||||
#### Using Eleven v3 with Audio Tags
|
||||
|
||||
Eleven v3 supports [audio tags](https://elevenlabs.io/docs/overview/capabilities/text-to-speech#audio-tags) for adding sound effects and pauses directly in the text:
|
||||
|
||||
```python showLineNumbers title="Eleven v3 with audio tags"
|
||||
import litellm
|
||||
import os
|
||||
|
||||
os.environ["ELEVENLABS_API_KEY"] = "your-elevenlabs-api-key"
|
||||
|
||||
audio = litellm.speech(
|
||||
model="elevenlabs/eleven_v3",
|
||||
input='Welcome back. <sfx>applause</sfx> Today we have a special guest. <pause duration="1.5s"/> Let me introduce them.',
|
||||
voice="alloy",
|
||||
)
|
||||
|
||||
with open("eleven_v3_output.mp3", "wb") as f:
|
||||
f.write(audio.read())
|
||||
```
|
||||
|
||||
#### Advanced Usage: Overriding Parameters and ElevenLabs-Specific Features
|
||||
|
||||
```python showLineNumbers title="Advanced TTS with custom parameters"
|
||||
|
|
|
|||
|
|
@ -35,11 +35,10 @@ from litellm import completion
|
|||
|
||||
response = completion(
|
||||
model="github_copilot/gpt-4",
|
||||
messages=[{"role": "user", "content": "Write a Python function to calculate fibonacci numbers"}],
|
||||
extra_headers={
|
||||
"editor-version": "vscode/1.85.1",
|
||||
"Copilot-Integration-Id": "vscode-chat"
|
||||
}
|
||||
messages=[
|
||||
{"role": "system", "content": "You are a helpful coding assistant"},
|
||||
{"role": "user", "content": "Write a Python function to calculate fibonacci numbers"}
|
||||
]
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
|
@ -50,11 +49,7 @@ from litellm import completion
|
|||
stream = completion(
|
||||
model="github_copilot/gpt-4",
|
||||
messages=[{"role": "user", "content": "Explain async/await in Python"}],
|
||||
stream=True,
|
||||
extra_headers={
|
||||
"editor-version": "vscode/1.85.1",
|
||||
"Copilot-Integration-Id": "vscode-chat"
|
||||
}
|
||||
stream=True
|
||||
)
|
||||
|
||||
for chunk in stream:
|
||||
|
|
@ -134,11 +129,7 @@ client = OpenAI(
|
|||
# Non-streaming response
|
||||
response = client.chat.completions.create(
|
||||
model="github_copilot/gpt-4",
|
||||
messages=[{"role": "user", "content": "How do I optimize this SQL query?"}],
|
||||
extra_headers={
|
||||
"editor-version": "vscode/1.85.1",
|
||||
"Copilot-Integration-Id": "vscode-chat"
|
||||
}
|
||||
messages=[{"role": "user", "content": "How do I optimize this SQL query?"}]
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
|
|
@ -156,11 +147,7 @@ response = litellm.completion(
|
|||
model="litellm_proxy/github_copilot/gpt-4",
|
||||
messages=[{"role": "user", "content": "Review this code for bugs"}],
|
||||
api_base="http://localhost:4000",
|
||||
api_key="your-proxy-api-key",
|
||||
extra_headers={
|
||||
"editor-version": "vscode/1.85.1",
|
||||
"Copilot-Integration-Id": "vscode-chat"
|
||||
}
|
||||
api_key="your-proxy-api-key"
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
|
|
@ -174,8 +161,6 @@ print(response.choices[0].message.content)
|
|||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer your-proxy-api-key" \
|
||||
-H "editor-version: vscode/1.85.1" \
|
||||
-H "Copilot-Integration-Id: vscode-chat" \
|
||||
-d '{
|
||||
"model": "github_copilot/gpt-4",
|
||||
"messages": [{"role": "user", "content": "Explain this error message"}]
|
||||
|
|
@ -211,9 +196,11 @@ export GITHUB_COPILOT_API_KEY_FILE="api-key.json"
|
|||
|
||||
### Headers
|
||||
|
||||
GitHub Copilot supports various editor-specific headers:
|
||||
LiteLLM automatically injects the required GitHub Copilot headers (simulating VSCode). You don't need to specify them manually.
|
||||
|
||||
```python showLineNumbers title="Common Headers"
|
||||
If you want to override the defaults (e.g., to simulate a different editor), you can use `extra_headers`:
|
||||
|
||||
```python showLineNumbers title="Custom Headers (Optional)"
|
||||
extra_headers = {
|
||||
"editor-version": "vscode/1.85.1", # Editor version
|
||||
"editor-plugin-version": "copilot/1.155.0", # Plugin version
|
||||
|
|
|
|||
|
|
@ -227,6 +227,28 @@ response = litellm.completion(
|
|||
)
|
||||
```
|
||||
|
||||
## OAuth2/JWT Authentication
|
||||
|
||||
If your LiteLLM Proxy requires OAuth2/JWT authentication (e.g., Azure AD, Keycloak, Okta), the SDK can automatically obtain and refresh tokens for you.
|
||||
|
||||
```python
|
||||
import litellm
|
||||
from litellm.proxy_auth import AzureADCredential, ProxyAuthHandler
|
||||
|
||||
litellm.proxy_auth = ProxyAuthHandler(
|
||||
credential=AzureADCredential(),
|
||||
scope="api://my-litellm-proxy/.default"
|
||||
)
|
||||
litellm.api_base = "https://my-proxy.example.com"
|
||||
|
||||
response = litellm.completion(
|
||||
model="gpt-4",
|
||||
messages=[{"role": "user", "content": "Hello!"}]
|
||||
)
|
||||
```
|
||||
|
||||
[Learn more about SDK Proxy Authentication (OAuth2/JWT Auto-Refresh) →](../proxy_auth)
|
||||
|
||||
## Sending `tags` to LiteLLM Proxy
|
||||
|
||||
Tags allow you to categorize and track your API requests for monitoring, debugging, and analytics purposes. You can send tags as a list of strings to the LiteLLM Proxy using the `extra_body` parameter.
|
||||
|
|
|
|||
|
|
@ -230,7 +230,70 @@ os.environ["OPENAI_BASE_URL"] = "https://your_host/v1" # OPTIONAL
|
|||
|
||||
These also support the `OPENAI_BASE_URL` environment variable, which can be used to specify a custom API endpoint.
|
||||
|
||||
## OpenAI Vision Models
|
||||
### OpenAI Web Search Models
|
||||
|
||||
OpenAI has two ways to use web search, depending on the endpoint:
|
||||
|
||||
| Approach | Endpoint | Models | How to enable |
|
||||
|----------|----------|--------|---------------|
|
||||
| **Search Models** | `/chat/completions` | `gpt-5-search-api`, `gpt-4o-search-preview`, `gpt-4o-mini-search-preview` | Pass `web_search_options` parameter |
|
||||
| **Web Search Tool** | `/responses` | `gpt-5`, `gpt-4.1`, `gpt-4o`, and other regular models | Pass `web_search_preview` tool |
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk-completion" label="SDK - /chat/completions">
|
||||
|
||||
```python showLineNumbers
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="openai/gpt-5-search-api",
|
||||
messages=[{"role": "user", "content": "What is the capital of France?"}],
|
||||
web_search_options={
|
||||
"search_context_size": "medium" # Options: "low", "medium", "high"
|
||||
}
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sdk-responses" label="SDK - /responses">
|
||||
|
||||
```python showLineNumbers
|
||||
from litellm import responses
|
||||
|
||||
response = responses(
|
||||
model="openai/gpt-5",
|
||||
input="What is the capital of France?",
|
||||
tools=[{
|
||||
"type": "web_search_preview",
|
||||
"search_context_size": "low"
|
||||
}]
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
# Search model for /chat/completions
|
||||
- model_name: gpt-5-search-api
|
||||
litellm_params:
|
||||
model: openai/gpt-5-search-api
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
# Regular model for /responses with web_search_preview tool
|
||||
- model_name: gpt-5
|
||||
litellm_params:
|
||||
model: openai/gpt-5
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
For full details, see the [Web Search guide](../completion/web_search.md).
|
||||
|
||||
## OpenAI Vision Models
|
||||
| Model Name | Function Call |
|
||||
|-----------------------|-----------------------------------------------------------------|
|
||||
| gpt-4o | `response = completion(model="gpt-4o", messages=messages)` |
|
||||
|
|
|
|||
|
|
@ -37,6 +37,24 @@ for event in response:
|
|||
print(event)
|
||||
```
|
||||
|
||||
#### Web Search
|
||||
```python showLineNumbers title="OpenAI Responses with Web Search"
|
||||
import litellm
|
||||
|
||||
response = litellm.responses(
|
||||
model="openai/gpt-5",
|
||||
input="What is the capital of France?",
|
||||
tools=[{
|
||||
"type": "web_search_preview",
|
||||
"search_context_size": "medium" # Options: "low", "medium", "high"
|
||||
}]
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
For full details, see the [Web Search guide](../../completion/web_search.md).
|
||||
|
||||
#### Image Generation with Streaming
|
||||
```python showLineNumbers title="OpenAI Streaming Image Generation"
|
||||
import litellm
|
||||
|
|
|
|||
|
|
@ -120,6 +120,293 @@ All models listed here https://docs.perplexity.ai/docs/model-cards are supported
|
|||
|
||||
|
||||
|
||||
## Agentic Research API (Responses API)
|
||||
|
||||
Requires v1.72.6+
|
||||
|
||||
|
||||
### Using Presets
|
||||
|
||||
Presets provide optimized defaults for specific use cases. Start with a preset for quick setup:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
# Using the pro-search preset
|
||||
response = responses(
|
||||
model="perplexity/preset/pro-search",
|
||||
input="What are the latest developments in AI?",
|
||||
custom_llm_provider="perplexity",
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="Proxy">
|
||||
|
||||
1. Setup config.yaml
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: perplexity-pro-search
|
||||
litellm_params:
|
||||
model: perplexity/preset/pro-search
|
||||
api_key: os.environ/PERPLEXITY_API_KEY
|
||||
```
|
||||
|
||||
2. Start proxy
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
3. Test it!
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/responses \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer anything" \
|
||||
-d '{
|
||||
"model": "perplexity-pro-search",
|
||||
"input": "What are the latest developments in AI?"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Using Third-Party Models
|
||||
|
||||
Access models from OpenAI, Anthropic, Google, xAI, and other providers through Perplexity's unified API:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="openai" label="OpenAI">
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/openai/gpt-4o",
|
||||
input="Explain quantum computing in simple terms",
|
||||
custom_llm_provider="perplexity",
|
||||
max_output_tokens=500,
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="anthropic" label="Anthropic">
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/anthropic/claude-3-5-sonnet-20241022",
|
||||
input="Write a short story about a robot learning to paint",
|
||||
custom_llm_provider="perplexity",
|
||||
max_output_tokens=500,
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="google" label="Google">
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/google/gemini-2.0-flash-exp",
|
||||
input="Explain the concept of neural networks",
|
||||
custom_llm_provider="perplexity",
|
||||
max_output_tokens=500,
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="xai" label="xAI">
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/xai/grok-2-1212",
|
||||
input="What makes a good AI assistant?",
|
||||
custom_llm_provider="perplexity",
|
||||
max_output_tokens=500,
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Web Search Tool
|
||||
|
||||
Enable web search capabilities to access real-time information:
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/openai/gpt-4o",
|
||||
input="What's the weather in San Francisco today?",
|
||||
custom_llm_provider="perplexity",
|
||||
tools=[{"type": "web_search"}],
|
||||
instructions="You have access to a web_search tool. Use it for questions about current events.",
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
|
||||
### Reasoning Effort (Responses API)
|
||||
|
||||
Control the reasoning effort level for reasoning-capable models:
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/openai/gpt-5.2",
|
||||
input="Solve this complex problem step by step",
|
||||
custom_llm_provider="perplexity",
|
||||
reasoning={"effort": "high"}, # Options: low, medium, high
|
||||
max_output_tokens=1000,
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
### Multi-Turn Conversations
|
||||
|
||||
Use message arrays for multi-turn conversations with context:
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/anthropic/claude-3-5-sonnet-20241022",
|
||||
input=[
|
||||
{"type": "message", "role": "system", "content": "You are a helpful assistant."},
|
||||
{"type": "message", "role": "user", "content": "What are the latest AI developments?"},
|
||||
],
|
||||
custom_llm_provider="perplexity",
|
||||
instructions="Provide detailed, well-researched answers.",
|
||||
max_output_tokens=800,
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
### Streaming Responses
|
||||
|
||||
Stream responses for real-time output:
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/openai/gpt-4o",
|
||||
input="Tell me a story about space exploration",
|
||||
custom_llm_provider="perplexity",
|
||||
stream=True,
|
||||
max_output_tokens=500,
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
if hasattr(chunk, 'type'):
|
||||
if chunk.type == "response.output_text.delta":
|
||||
print(chunk.delta, end="", flush=True)
|
||||
```
|
||||
|
||||
### Supported Third-Party Models
|
||||
|
||||
| Provider | Model Name | Function Call |
|
||||
|----------|------------|---------------|
|
||||
| OpenAI | gpt-4o | `responses(model="perplexity/openai/gpt-4o", ...)` |
|
||||
| OpenAI | gpt-4o-mini | `responses(model="perplexity/openai/gpt-4o-mini", ...)` |
|
||||
| OpenAI | gpt-5.2 | `responses(model="perplexity/openai/gpt-5.2", ...)` |
|
||||
| Anthropic | claude-3-5-sonnet-20241022 | `responses(model="perplexity/anthropic/claude-3-5-sonnet-20241022", ...)` |
|
||||
| Anthropic | claude-3-5-haiku-20241022 | `responses(model="perplexity/anthropic/claude-3-5-haiku-20241022", ...)` |
|
||||
| Google | gemini-2.0-flash-exp | `responses(model="perplexity/google/gemini-2.0-flash-exp", ...)` |
|
||||
| Google | gemini-2.0-flash-thinking-exp | `responses(model="perplexity/google/gemini-2.0-flash-thinking-exp", ...)` |
|
||||
| xAI | grok-2-1212 | `responses(model="perplexity/xai/grok-2-1212", ...)` |
|
||||
| xAI | grok-2-vision-1212 | `responses(model="perplexity/xai/grok-2-vision-1212", ...)` |
|
||||
|
||||
### Available Presets
|
||||
|
||||
| Preset Name | Function Call |
|
||||
|----------------|--------------------------------------------------------|
|
||||
| fast-search | `responses(model="perplexity/preset/fast-search", ...)`|
|
||||
| pro-search | `responses(model="perplexity/preset/pro-search", ...)` |
|
||||
| deep-research | `responses(model="perplexity/preset/deep-research", ...)`|
|
||||
|
||||
### Complete Example
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
# Comprehensive example with multiple features
|
||||
response = responses(
|
||||
model="perplexity/openai/gpt-4o",
|
||||
input="Research the latest developments in quantum computing and provide sources",
|
||||
custom_llm_provider="perplexity",
|
||||
tools=[
|
||||
{"type": "web_search"},
|
||||
{"type": "fetch_url"}
|
||||
],
|
||||
instructions="Use web_search to find relevant information and fetch_url to retrieve detailed content from sources. Provide citations for all claims.",
|
||||
max_output_tokens=1000,
|
||||
temperature=0.7,
|
||||
)
|
||||
|
||||
print(f"Response ID: {response.id}")
|
||||
print(f"Model: {response.model}")
|
||||
print(f"Status: {response.status}")
|
||||
print(f"Output: {response.output}")
|
||||
print(f"Usage: {response.usage}")
|
||||
```
|
||||
|
||||
:::info
|
||||
|
||||
For more information about passing provider-specific parameters, [go here](../completion/provider_specific_params.md)
|
||||
|
|
|
|||
62
docs/my-website/docs/providers/scaleway.md
Normal file
|
|
@ -0,0 +1,62 @@
|
|||
|
||||
# Scaleway
|
||||
LiteLLM supports all [models available on Scaleway Generative APIs ↗](https://www.scaleway.com/en/docs/generative-apis/reference-content/supported-models/).
|
||||
|
||||
## Usage with LiteLLM Python SDK
|
||||
|
||||
```python
|
||||
import os
|
||||
from litellm import completion
|
||||
|
||||
os.environ["SCW_SECRET_KEY"] = "your-scaleway-secret-key"
|
||||
|
||||
messages = [{"role": "user", "content": "Write a short poem"}]
|
||||
response = completion(model="scaleway/qwen3-235b-a22b-instruct-2507", messages=messages)
|
||||
print(response)
|
||||
```
|
||||
|
||||
## Usage with LiteLLM Proxy
|
||||
|
||||
### 1. Set Scaleway models in config.yaml
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: scaleway-model
|
||||
litellm_params:
|
||||
model: scaleway/qwen3-235b-a22b-instruct-2507
|
||||
api_key: "os.environ/SCW_SECRET_KEY" # ensure you have `SCW_SECRET_KEY` in your .env
|
||||
```
|
||||
|
||||
### 2. Start proxy
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
### 3. Query proxy
|
||||
|
||||
Assuming the proxy is running on [http://localhost:4000](http://localhost:4000):
|
||||
```bash
|
||||
curl http://localhost:4000/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer YOUR_LITELLM_MASTER_KEY" \
|
||||
-d '{
|
||||
"model": "scaleway-model",
|
||||
"messages": [
|
||||
{
|
||||
"role": "system",
|
||||
"content": "You are a helpful assistant."
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Write a short poem"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
`-H "Authorization: Bearer YOUR_LITELLM_MASTER_KEY" ` is only required if you have set a LiteLLM master key
|
||||
|
||||
|
||||
## Supported features
|
||||
|
||||
Scaleway provider supports all features in [Generative APIs reference documentation ↗](https://www.scaleway.com/en/developers/api/generative-apis/), such as streaming, structured outputs and tool calling.
|
||||
308
docs/my-website/docs/providers/xai_realtime.md
Normal file
|
|
@ -0,0 +1,308 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# xAI Voice Agent (Realtime API)
|
||||
|
||||
xAI's Grok Voice Agent provides real-time voice conversation capabilities through WebSocket connections, enabling natural bidirectional audio interactions.
|
||||
|
||||
| Feature | Description | Comments |
|
||||
| --- | --- | --- |
|
||||
| LiteLLM AI Gateway | ✅ | |
|
||||
| LiteLLM Python SDK | ✅ | Full support via `litellm.realtime()` |
|
||||
|
||||
## Quick Start
|
||||
|
||||
### Supported Model
|
||||
|
||||
| Model | Context | Features |
|
||||
|-------|---------|----------|
|
||||
| `xai/grok-4-1-fast-non-reasoning` | 2M tokens | Voice conversation, Function calling, Vision, Audio, Web search, Caching |
|
||||
|
||||
**Note:** xAI Realtime API uses the non-reasoning variant for optimal real-time performance.
|
||||
|
||||
## Python SDK Usage
|
||||
|
||||
### Basic Realtime Connection
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
from litellm import realtime
|
||||
|
||||
async def test_xai_realtime():
|
||||
"""
|
||||
Test xAI Grok Voice Agent via LiteLLM SDK
|
||||
"""
|
||||
# Initialize realtime connection
|
||||
ws = await realtime(
|
||||
model="xai/grok-4-1-fast-non-reasoning",
|
||||
api_key="your-xai-api-key", # or set XAI_API_KEY env var
|
||||
)
|
||||
|
||||
# Connection established, xAI sends "conversation.created" event
|
||||
print("Connected to xAI Grok Voice Agent")
|
||||
|
||||
# Send a message
|
||||
await ws.send_text(json.dumps({
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{
|
||||
"type": "input_text",
|
||||
"text": "Hello! How are you?"
|
||||
}]
|
||||
}
|
||||
}))
|
||||
|
||||
# Request a response
|
||||
await ws.send_text(json.dumps({
|
||||
"type": "response.create"
|
||||
}))
|
||||
|
||||
# Listen for responses
|
||||
async for message in ws:
|
||||
data = json.loads(message)
|
||||
print(f"Received: {data['type']}")
|
||||
|
||||
if data['type'] == 'response.done':
|
||||
break
|
||||
|
||||
await ws.close()
|
||||
|
||||
# Run the async function
|
||||
asyncio.run(test_xai_realtime())
|
||||
```
|
||||
|
||||
### With Audio Input/Output
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
import json
|
||||
from litellm import realtime
|
||||
|
||||
async def xai_voice_conversation():
|
||||
"""
|
||||
Voice conversation with xAI Grok Voice Agent
|
||||
"""
|
||||
ws = await realtime(
|
||||
model="xai/grok-4-1-fast-non-reasoning",
|
||||
api_key="your-xai-api-key",
|
||||
)
|
||||
|
||||
# Send audio data (base64 encoded PCM16 24kHz)
|
||||
await ws.send_text(json.dumps({
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{
|
||||
"type": "input_audio",
|
||||
"audio": "base64_encoded_audio_data_here"
|
||||
}]
|
||||
}
|
||||
}))
|
||||
|
||||
# Request response with audio
|
||||
await ws.send_text(json.dumps({
|
||||
"type": "response.create",
|
||||
"response": {
|
||||
"modalities": ["text", "audio"],
|
||||
"instructions": "Please respond in a friendly tone."
|
||||
}
|
||||
}))
|
||||
|
||||
# Process streaming audio response
|
||||
async for message in ws:
|
||||
data = json.loads(message)
|
||||
|
||||
if data['type'] == 'response.audio.delta':
|
||||
# Handle audio chunks
|
||||
audio_chunk = data['delta']
|
||||
# Process audio_chunk (play it, save it, etc.)
|
||||
|
||||
elif data['type'] == 'response.done':
|
||||
break
|
||||
|
||||
await ws.close()
|
||||
|
||||
asyncio.run(xai_voice_conversation())
|
||||
```
|
||||
|
||||
## LiteLLM Proxy (AI Gateway) Usage
|
||||
|
||||
Load balance across multiple xAI deployments or combine with other providers.
|
||||
|
||||
### 1. Add Model to Config
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: grok-voice-agent
|
||||
litellm_params:
|
||||
model: xai/grok-4-1-fast-non-reasoning
|
||||
api_key: os.environ/XAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
|
||||
# Optional: Add fallback to OpenAI
|
||||
- model_name: grok-voice-agent
|
||||
litellm_params:
|
||||
model: openai/gpt-4o-realtime-preview-2024-10-01
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
```
|
||||
|
||||
### 2. Start Proxy
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
### 3. Test Connection
|
||||
|
||||
#### Python Client
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
import websockets
|
||||
import json
|
||||
|
||||
async def test_proxy():
|
||||
url = "ws://0.0.0.0:4000/v1/realtime?model=grok-voice-agent"
|
||||
|
||||
async with websockets.connect(
|
||||
url,
|
||||
extra_headers={
|
||||
"Authorization": "Bearer sk-1234", # Your LiteLLM proxy key
|
||||
"OpenAI-Beta": "realtime=v1"
|
||||
}
|
||||
) as ws:
|
||||
# Wait for conversation.created event from xAI
|
||||
message = await ws.recv()
|
||||
print(f"Connected: {message}")
|
||||
|
||||
# Send a message
|
||||
await ws.send(json.dumps({
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{
|
||||
"type": "input_text",
|
||||
"text": "Hello from LiteLLM proxy!"
|
||||
}]
|
||||
}
|
||||
}))
|
||||
|
||||
# Request response
|
||||
await ws.send(json.dumps({
|
||||
"type": "response.create"
|
||||
}))
|
||||
|
||||
# Listen for response
|
||||
async for message in ws:
|
||||
data = json.loads(message)
|
||||
print(f"Event: {data['type']}")
|
||||
|
||||
if data['type'] == 'response.done':
|
||||
break
|
||||
|
||||
asyncio.run(test_proxy())
|
||||
```
|
||||
|
||||
#### Node.js Client
|
||||
|
||||
```javascript
|
||||
// test.js - Run with: node test.js
|
||||
const WebSocket = require("ws");
|
||||
|
||||
const url = "ws://0.0.0.0:4000/v1/realtime?model=grok-voice-agent";
|
||||
|
||||
const ws = new WebSocket(url, {
|
||||
headers: {
|
||||
"Authorization": "Bearer sk-1234",
|
||||
"OpenAI-Beta": "realtime=v1",
|
||||
},
|
||||
});
|
||||
|
||||
ws.on("open", function open() {
|
||||
console.log("Connected to xAI via LiteLLM proxy");
|
||||
|
||||
// Send a message
|
||||
ws.send(JSON.stringify({
|
||||
type: "conversation.item.create",
|
||||
item: {
|
||||
type: "message",
|
||||
role: "user",
|
||||
content: [{
|
||||
type: "input_text",
|
||||
text: "What's the weather like?"
|
||||
}]
|
||||
}
|
||||
}));
|
||||
|
||||
// Request response
|
||||
ws.send(JSON.stringify({
|
||||
type: "response.create",
|
||||
response: {
|
||||
modalities: ["text"],
|
||||
instructions: "Please assist the user."
|
||||
}
|
||||
}));
|
||||
});
|
||||
|
||||
ws.on("message", function incoming(message) {
|
||||
const data = JSON.parse(message.toString());
|
||||
console.log(`Event: ${data.type}`);
|
||||
|
||||
if (data.type === 'response.done') {
|
||||
ws.close();
|
||||
}
|
||||
});
|
||||
|
||||
ws.on("error", function handleError(error) {
|
||||
console.error("Error: ", error);
|
||||
});
|
||||
```
|
||||
|
||||
## Key Differences from OpenAI
|
||||
|
||||
xAI's Grok Voice Agent has some differences from OpenAI's Realtime API:
|
||||
|
||||
| Feature | xAI | OpenAI | LiteLLM Handling |
|
||||
|---------|-----|--------|------------------|
|
||||
| Initial Event | `conversation.created` | `session.created` | ⚠️ Passed through as-is |
|
||||
| WebSocket URL | `wss://api.x.ai/v1/realtime` | `wss://api.openai.com/v1/realtime` | ✅ Auto-configured |
|
||||
| Model | `grok-4-1-fast-non-reasoning` | `gpt-4o-realtime-preview` | ✅ Via model prefix |
|
||||
| Audio Format | PCM16 24kHz mono | PCM16 24kHz mono | ✅ Compatible |
|
||||
| Context Window | 2M tokens | 128K tokens | N/A |
|
||||
|
||||
**What LiteLLM Handles:**
|
||||
- ✅ Automatic URL routing to correct provider
|
||||
- ✅ Authentication headers (no `OpenAI-Beta` header for xAI)
|
||||
- ✅ WebSocket connection management
|
||||
- ✅ All other event types are compatible
|
||||
|
||||
**What You Need to Handle:**
|
||||
- ⚠️ Initial event type difference (`conversation.created` vs `session.created`)
|
||||
|
||||
**Tip:** Make your client compatible with both event types:
|
||||
```python
|
||||
# Handle both providers
|
||||
if event['type'] in ['session.created', 'conversation.created']:
|
||||
print("Connection established")
|
||||
```
|
||||
|
||||
## Related Documentation
|
||||
|
||||
- [xAI Chat/Text Models](/docs/providers/xai)
|
||||
- [LiteLLM Realtime API Overview](/docs/realtime)
|
||||
- [xAI Official Documentation](https://docs.x.ai/docs)
|
||||
|
||||
## Support
|
||||
|
||||
For issues or questions:
|
||||
- [LiteLLM GitHub Issues](https://github.com/BerriAI/litellm/issues)
|
||||
- [xAI Documentation](https://docs.x.ai/docs)
|
||||
122
docs/my-website/docs/proxy/access_groups.md
Normal file
|
|
@ -0,0 +1,122 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Access Groups
|
||||
|
||||
Access Groups simplify how you define and manage resource access across your organization. Instead of configuring models, MCP servers, and agents separately on each key or team, you create one group that bundles the resources you want to grant, then attach that group to your keys or teams.
|
||||
|
||||
## Overview
|
||||
|
||||
**Access Groups** let you define a reusable set of allowed resources—models, MCP servers, and agents—in a single place. One group can grant access to all three resource types. Simply attach the group to a key or team, and they get access to everything defined in that group.
|
||||
|
||||
- **Unified resource control** – One group controls access to models, MCP servers, and agents together
|
||||
- **Reusable** – Define once, attach to many keys or teams
|
||||
- **Easy to maintain** – Update the group (add or remove resources) and all attached keys and teams automatically reflect the change
|
||||
- **Clear visibility** – See exactly which resources each group grants and which keys/teams use it
|
||||
|
||||
<Image img={require('../../img/ui_access_groups.png')} />
|
||||
|
||||
### How It Works
|
||||
|
||||
**Key concept:** Define resources in a group → Attach group to key or team → Key/team gets access to all resources in the group
|
||||
|
||||
| Resource Type | What the group controls |
|
||||
| --------------- | -------------------------------------------------------------------- |
|
||||
| **Models** | Which LLM models keys/teams can use (e.g., `gpt-4`, `claude-3-opus`) |
|
||||
| **MCP Servers** | Which MCP servers are available for tool calling |
|
||||
| **Agents** | Which agents can be invoked |
|
||||
|
||||
## How to Create and Use Access Groups in the UI
|
||||
|
||||
### 1. Navigate to Access Groups
|
||||
|
||||
Go to the Admin UI (e.g. `http://localhost:4000/ui` or your `PROXY_BASE_URL/ui`) and click **Access Groups** in the sidebar.
|
||||
|
||||
|
||||
|
||||
### 2. Create an Access Group
|
||||
|
||||
Click **Create Access Group** and give your group a name.
|
||||
|
||||
|
||||
|
||||
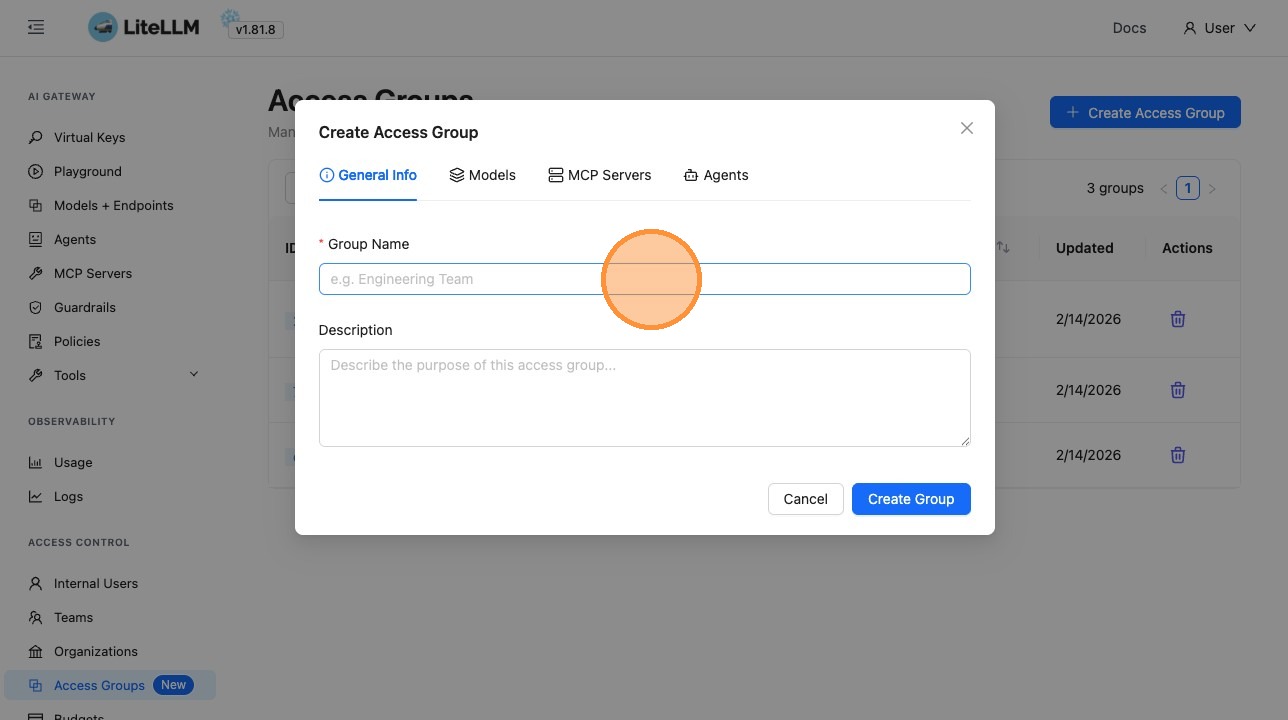
|
||||
|
||||
### 3. Define Resources in the Group
|
||||
|
||||
Use the tabs to select which models, MCP servers, and agents this group grants access to:
|
||||
|
||||
- **Models tab** – Select the LLM models
|
||||
- **MCP Servers tab** – Select MCP servers (for tool calling)
|
||||
- **Agents tab** – Select agents
|
||||
|
||||
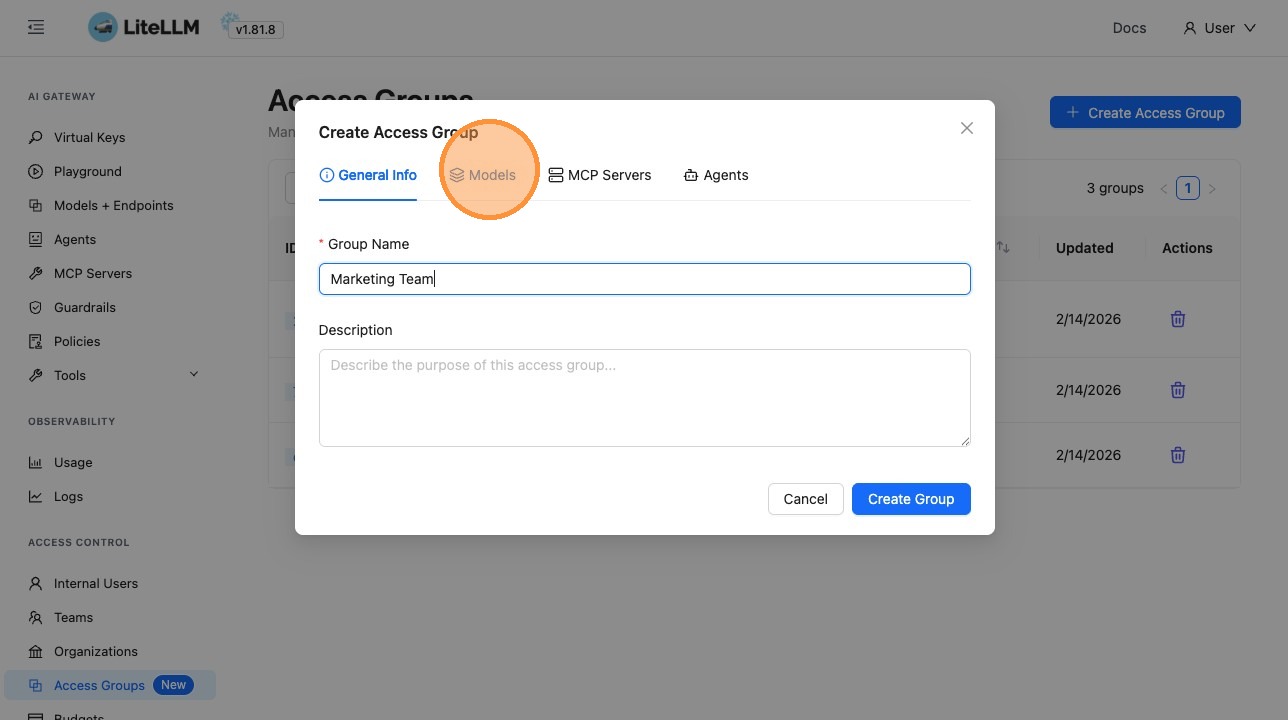
|
||||
|
||||
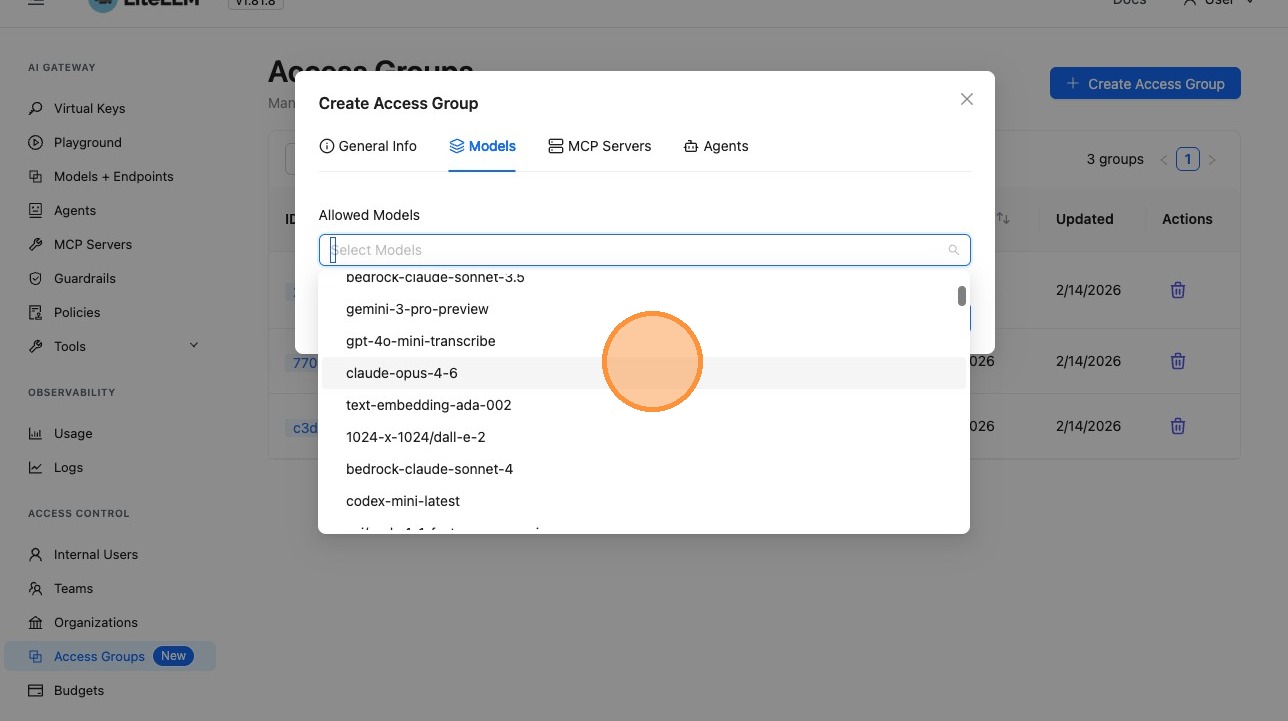
|
||||
|
||||
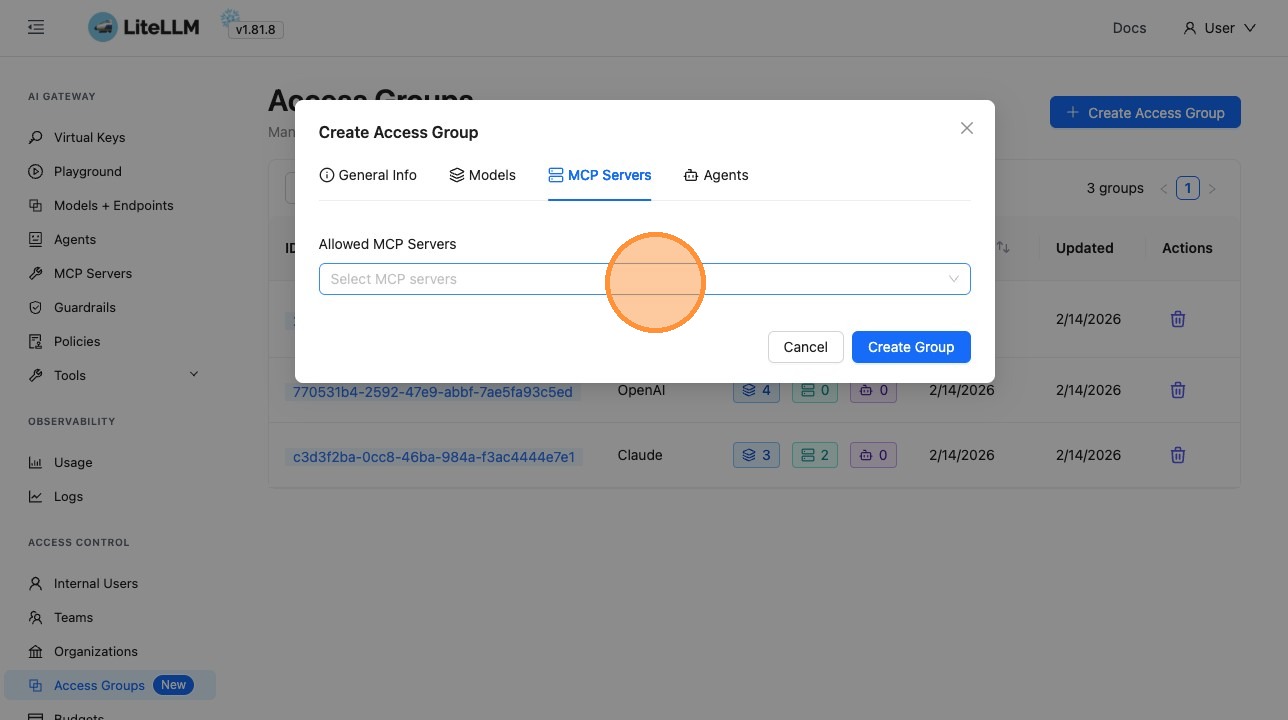
|
||||
|
||||
### 4. Attach the Access Group to a Key
|
||||
|
||||
When creating or editing a virtual key, expand **Optional Settings** and select your Access Group. The key will inherit access to all models, MCP servers, and agents defined in that group.
|
||||
|
||||
1. Go to **Virtual Keys** and click **+ Create New Key**
|
||||
2. Expand **Optional Settings**
|
||||
3. In the Access Group field, select the group you created
|
||||
4. Save the key
|
||||
|
||||
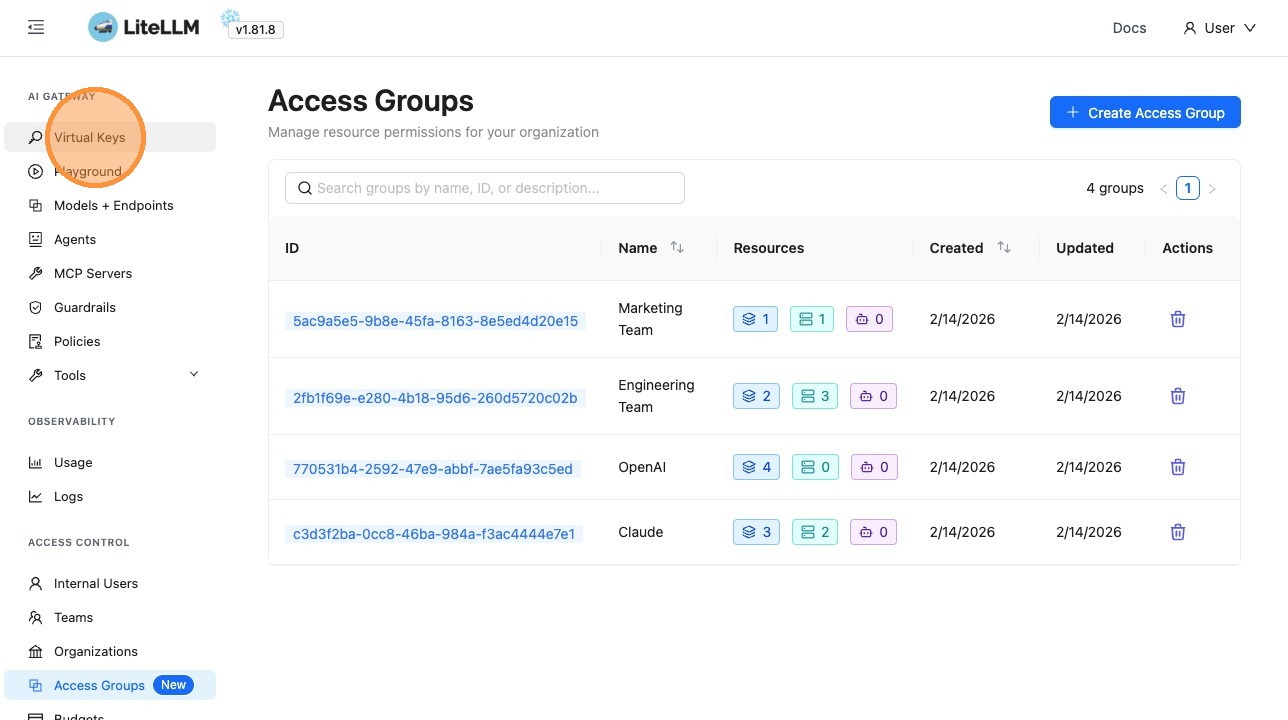
|
||||
|
||||
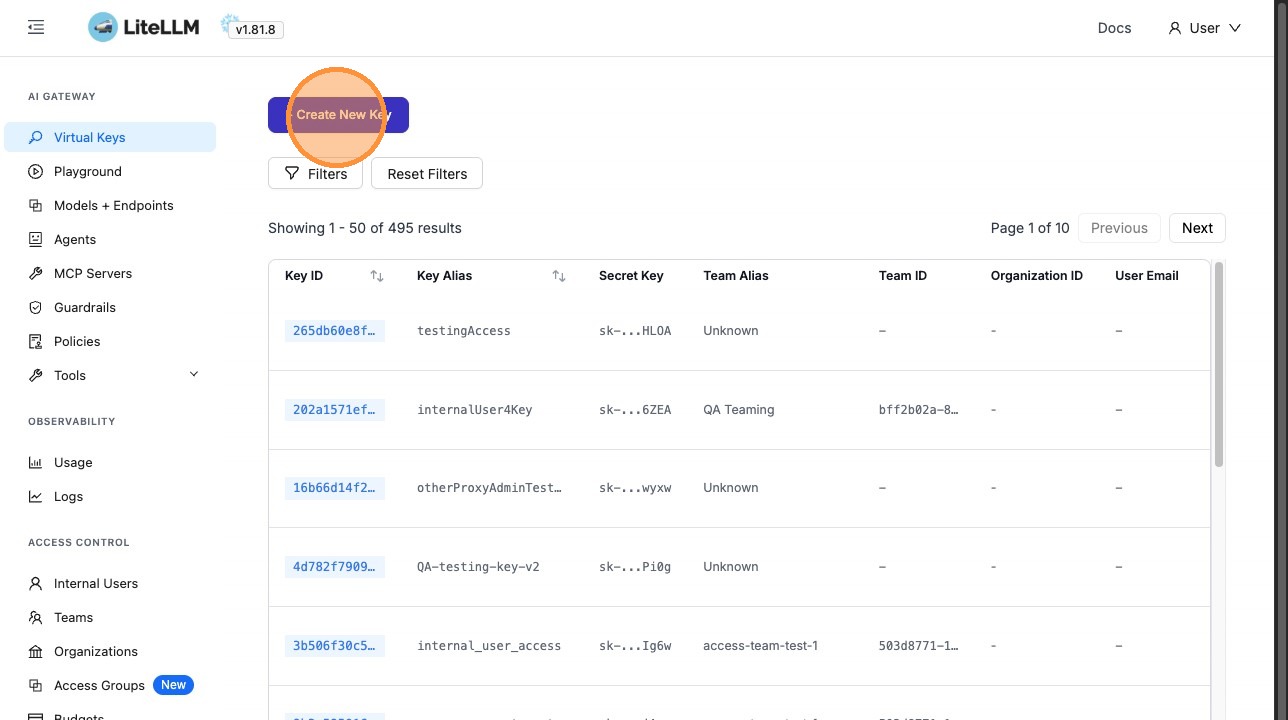
|
||||
|
||||
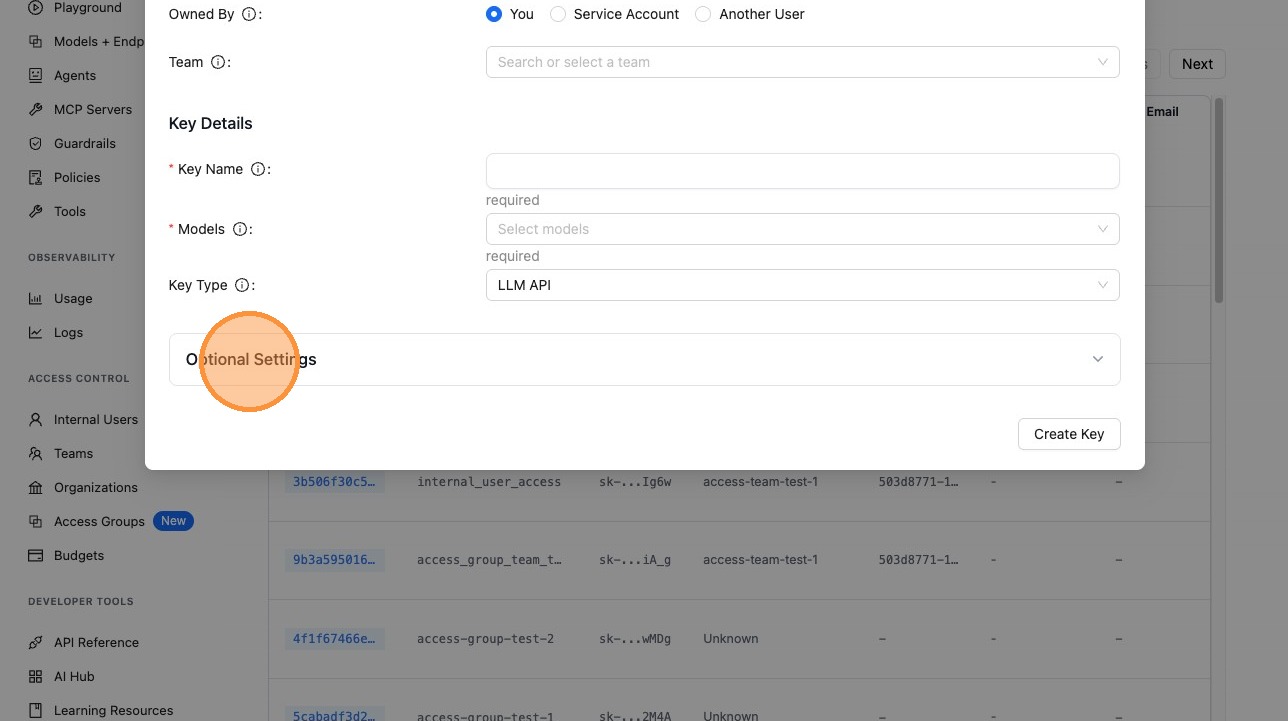
|
||||
|
||||
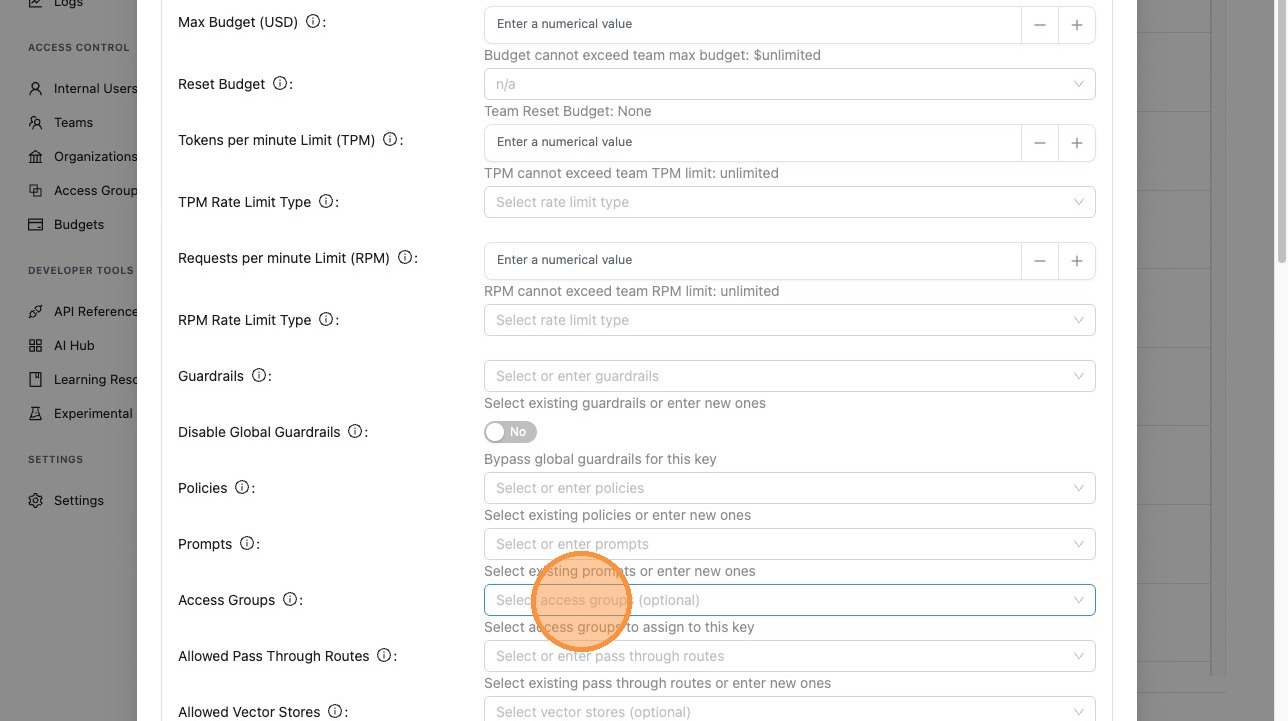
|
||||
|
||||
|
||||
|
||||
### 5. Attach the Access Group to a Team
|
||||
|
||||
You can also attach an Access Group to a team when creating or editing the team. All keys associated with that team will then have access to the resources defined in the group.
|
||||
|
||||
## Use Cases
|
||||
|
||||
### Team-based Access
|
||||
|
||||
Create groups like "Engineering", "Data Science", or "Product" with the models, MCP servers, and agents each team needs. Attach the group to the team—no need to configure each resource on every key.
|
||||
|
||||
### Environment Separation
|
||||
|
||||
- **Production group** – Production models, approved MCP servers, and production agents
|
||||
- **Development group** – Cost-efficient models, experimental MCP tools, and dev agents
|
||||
|
||||
Attach the appropriate group to keys or teams based on environment.
|
||||
|
||||
### Simplified Onboarding
|
||||
|
||||
New developers get a key with an Access Group instead of manually configuring models, MCP servers, and agents. Add them to the right team or give them a key with the correct group.
|
||||
|
||||
### Centralized Updates
|
||||
|
||||
When you add a new model or MCP server to a group, every key and team attached to that group automatically gains access. Remove a resource from the group and it’s revoked everywhere at once.
|
||||
|
||||
## Access Group vs. Model Access Groups
|
||||
|
||||
LiteLLM has two related concepts:
|
||||
|
||||
| Feature | **Access Groups** (this page) | **Model Access Groups** |
|
||||
| ---------- | ----------------------------------------------------------------------- | ------------------------------------------------------- |
|
||||
| Definition | Define in the UI; one group can include models, MCP servers, and agents | Defined in config or via API; groups are model-centric |
|
||||
| Scope | Models + MCP servers + agents | Models only |
|
||||
| Attach to | Keys, teams | Keys, teams |
|
||||
| Use when | You want unified control over models, MCP, and agents from the UI | You need config-based or API-based model access control |
|
||||
|
||||
For config-based model access with `access_groups` in `model_info`, see [Model Access Groups](./model_access_groups.md).
|
||||
|
||||
## Related Documentation
|
||||
|
||||
- [Virtual Keys](./virtual_keys.md) – Creating and managing API keys
|
||||
- [Role-based Access Controls](./access_control.md) – Organizations, teams, and user roles
|
||||
- [Model Access Groups](./model_access_groups.md) – Config-based model access groups
|
||||
- [MCP Control](../mcp_control.md) – MCP server setup and access control
|
||||
|
|
@ -23,26 +23,75 @@ From v1.76.0, SSO is now Free for up to 5 users.
|
|||
<Tabs>
|
||||
<TabItem value="okta" label="Okta SSO">
|
||||
|
||||
1. Add Okta credentials to your .env
|
||||
#### Step 1: Create an OIDC Application in Okta
|
||||
|
||||
In your Okta Admin Console, create a new **OIDC Web Application**. See [Okta's guide on creating OIDC app integrations](https://help.okta.com/en-us/content/topics/apps/apps_app_integration_wizard_oidc.htm) for detailed instructions.
|
||||
|
||||
When configuring the application:
|
||||
- **Sign-in redirect URI**: `https://<your-proxy-base-url>/sso/callback`
|
||||
- **Sign-out redirect URI** (optional): `https://<your-proxy-base-url>`
|
||||
|
||||
<Image img={require('../../img/okta_redirect_uri.png')} />
|
||||
|
||||
After creating the app, copy your **Client ID** and **Client Secret** from the application's General tab:
|
||||
|
||||
<Image img={require('../../img/okta_client_credentials.png')} />
|
||||
|
||||
#### Step 2: Assign Users to the Application
|
||||
|
||||
Ensure users are assigned to the app in the **Assignments** tab. If Federation Broker Mode is enabled, you may need to disable it to assign users manually.
|
||||
|
||||
#### Step 3: Configure Authorization Server Access Policy
|
||||
|
||||
:::warning Important
|
||||
This step is required. Without an Access Policy for your app, users will get a `no_matching_policy` error when attempting to log in.
|
||||
:::
|
||||
|
||||
1. Go to **Security** → **API**
|
||||
|
||||
<Image img={require('../../img/okta_security_api.png')} />
|
||||
|
||||
2. Select the **default** authorization server (or your custom one)
|
||||
|
||||
<Image img={require('../../img/okta_authorization_server.png')} />
|
||||
|
||||
3. Click on **Access Policies** tab, create a new policy assigned to your LiteLLM app
|
||||
4. Add a rule that allows the **Authorization Code** grant type
|
||||
|
||||
<Image img={require('../../img/okta_access_policies.png')} />
|
||||
|
||||
See [Okta's Access Policy documentation](https://help.okta.com/en-us/content/topics/security/api-access-management/access-policies.htm) for more details.
|
||||
|
||||
#### Step 4: Configure LiteLLM Environment Variables
|
||||
|
||||
```bash
|
||||
GENERIC_CLIENT_ID = "<your-okta-client-id>"
|
||||
GENERIC_CLIENT_SECRET = "<your-okta-client-secret>"
|
||||
GENERIC_AUTHORIZATION_ENDPOINT = "<your-okta-domain>/authorize" # https://dev-2kqkcd6lx6kdkuzt.us.auth0.com/authorize
|
||||
GENERIC_TOKEN_ENDPOINT = "<your-okta-domain>/token" # https://dev-2kqkcd6lx6kdkuzt.us.auth0.com/oauth/token
|
||||
GENERIC_USERINFO_ENDPOINT = "<your-okta-domain>/userinfo" # https://dev-2kqkcd6lx6kdkuzt.us.auth0.com/userinfo
|
||||
GENERIC_CLIENT_STATE = "random-string" # [OPTIONAL] REQUIRED BY OKTA, if not set random state value is generated
|
||||
GENERIC_SSO_HEADERS = "Content-Type=application/json, X-Custom-Header=custom-value" # [OPTIONAL] Comma-separated list of additional headers to add to the request - e.g. Content-Type=application/json, etc.
|
||||
GENERIC_CLIENT_ID="<your-client-id>"
|
||||
GENERIC_CLIENT_SECRET="<your-client-secret>"
|
||||
GENERIC_AUTHORIZATION_ENDPOINT="https://<your-okta-domain>/oauth2/default/v1/authorize"
|
||||
GENERIC_TOKEN_ENDPOINT="https://<your-okta-domain>/oauth2/default/v1/token"
|
||||
GENERIC_USERINFO_ENDPOINT="https://<your-okta-domain>/oauth2/default/v1/userinfo"
|
||||
GENERIC_CLIENT_STATE="random-string"
|
||||
PROXY_BASE_URL="https://<your-proxy-base-url>"
|
||||
```
|
||||
|
||||
You can get your domain specific auth/token/userinfo endpoints at `<YOUR-OKTA-DOMAIN>/.well-known/openid-configuration`
|
||||
:::tip
|
||||
You can find all OAuth endpoints at `https://<your-okta-domain>/.well-known/openid-configuration`
|
||||
:::
|
||||
|
||||
2. Add proxy url as callback_url on Okta
|
||||
#### Step 5: Test the SSO Flow
|
||||
|
||||
On Okta, add the 'callback_url' as `<proxy_base_url>/sso/callback`
|
||||
1. Start your LiteLLM proxy
|
||||
2. Navigate to `https://<your-proxy-base-url>/ui`
|
||||
3. Click the SSO login button
|
||||
4. Authenticate with Okta and verify you're redirected back to LiteLLM
|
||||
|
||||
#### Troubleshooting
|
||||
|
||||
<Image img={require('../../img/okta_callback_url.png')} />
|
||||
| Error | Cause | Solution |
|
||||
|-------|-------|----------|
|
||||
| `redirect_uri` error | Redirect URI not configured | Add `<proxy_base_url>/sso/callback` to Sign-in redirect URIs in Okta |
|
||||
| `access_denied` | User not assigned to app | Assign the user in the Assignments tab |
|
||||
| `no_matching_policy` | Missing Access Policy | Create an Access Policy in the Authorization Server (see Step 3) |
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="google" label="Google SSO">
|
||||
|
|
@ -174,6 +223,7 @@ GENERIC_USER_FIRST_NAME_ATTRIBUTE = "first_name"
|
|||
GENERIC_USER_LAST_NAME_ATTRIBUTE = "last_name"
|
||||
GENERIC_USER_ROLE_ATTRIBUTE = "given_role"
|
||||
GENERIC_USER_PROVIDER_ATTRIBUTE = "provider"
|
||||
GENERIC_USER_EXTRA_ATTRIBUTES = "department,employee_id,manager" # comma-separated list of additional fields to extract from SSO response
|
||||
GENERIC_CLIENT_STATE = "some-state" # if the provider needs a state parameter
|
||||
GENERIC_INCLUDE_CLIENT_ID = "false" # some providers enforce that the client_id is not in the body
|
||||
GENERIC_SCOPE = "openid profile email" # default scope openid is sometimes not enough to retrieve basic user info like first_name and last_name located in profile scope
|
||||
|
|
@ -190,6 +240,40 @@ Use `GENERIC_USER_ROLE_ATTRIBUTE` to specify which attribute in the SSO token co
|
|||
|
||||
Nested attribute paths are supported (e.g., `claims.role` or `attributes.litellm_role`).
|
||||
|
||||
**Capturing Additional SSO Fields**
|
||||
|
||||
Use `GENERIC_USER_EXTRA_ATTRIBUTES` to extract additional fields from the SSO provider response beyond the standard user attributes (id, email, name, etc.). This is useful when you need to access custom organization-specific data (e.g., department, employee ID, groups) in your [custom SSO handler](./custom_sso.md).
|
||||
|
||||
```shell
|
||||
# Comma-separated list of field names to extract
|
||||
GENERIC_USER_EXTRA_ATTRIBUTES="department,employee_id,manager,groups"
|
||||
```
|
||||
|
||||
**Accessing Extra Fields in Custom SSO Handler:**
|
||||
|
||||
```python
|
||||
from litellm.proxy.management_endpoints.types import CustomOpenID
|
||||
|
||||
async def custom_sso_handler(userIDPInfo: CustomOpenID):
|
||||
# Access the extra fields
|
||||
extra_fields = getattr(userIDPInfo, 'extra_fields', None) or {}
|
||||
|
||||
user_department = extra_fields.get("department")
|
||||
employee_id = extra_fields.get("employee_id")
|
||||
user_groups = extra_fields.get("groups", [])
|
||||
|
||||
# Use these fields for custom logic (e.g., team assignment, access control)
|
||||
# ...
|
||||
```
|
||||
|
||||
**Nested Field Paths:**
|
||||
|
||||
Dot notation is supported for nested fields:
|
||||
|
||||
```shell
|
||||
GENERIC_USER_EXTRA_ATTRIBUTES="org_info.department,org_info.cost_center,metadata.employee_type"
|
||||
```
|
||||
|
||||
- Set Redirect URI, if your provider requires it
|
||||
- Set a redirect url = `<your proxy base url>/sso/callback`
|
||||
```shell
|
||||
|
|
|
|||
|
|
@ -1,7 +1,10 @@
|
|||
# CLI Arguments
|
||||
Cli arguments, --host, --port, --num_workers
|
||||
|
||||
## --host
|
||||
This page documents all command-line interface (CLI) arguments available for the LiteLLM proxy server.
|
||||
|
||||
## Server Configuration
|
||||
|
||||
### --host
|
||||
- **Default:** `'0.0.0.0'`
|
||||
- The host for the server to listen on.
|
||||
- **Usage:**
|
||||
|
|
@ -14,7 +17,7 @@ Cli arguments, --host, --port, --num_workers
|
|||
litellm
|
||||
```
|
||||
|
||||
## --port
|
||||
### --port
|
||||
- **Default:** `4000`
|
||||
- The port to bind the server to.
|
||||
- **Usage:**
|
||||
|
|
@ -27,9 +30,9 @@ Cli arguments, --host, --port, --num_workers
|
|||
litellm
|
||||
```
|
||||
|
||||
## --num_workers
|
||||
- **Default:** `1`
|
||||
- The number of uvicorn workers to spin up.
|
||||
### --num_workers
|
||||
- **Default:** Number of logical CPUs in the system, or `4` if that cannot be determined
|
||||
- The number of uvicorn / gunicorn workers to spin up.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --num_workers 4
|
||||
|
|
@ -40,55 +43,273 @@ Cli arguments, --host, --port, --num_workers
|
|||
litellm
|
||||
```
|
||||
|
||||
## --api_base
|
||||
### --config
|
||||
- **Short form:** `-c`
|
||||
- **Default:** `None`
|
||||
- The API base for the model litellm should call.
|
||||
- Path to the proxy configuration file (e.g., config.yaml).
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --config path/to/config.yaml
|
||||
```
|
||||
|
||||
### --log_config
|
||||
- **Default:** `None`
|
||||
- **Type:** `str`
|
||||
- Path to the logging configuration file for uvicorn.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --log_config path/to/log_config.conf
|
||||
```
|
||||
|
||||
### --keepalive_timeout
|
||||
- **Default:** `None`
|
||||
- **Type:** `int`
|
||||
- Set the uvicorn keepalive timeout in seconds (uvicorn timeout_keep_alive parameter).
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --keepalive_timeout 30
|
||||
```
|
||||
- **Usage - set Environment Variable:** `KEEPALIVE_TIMEOUT`
|
||||
```shell
|
||||
export KEEPALIVE_TIMEOUT=30
|
||||
litellm
|
||||
```
|
||||
|
||||
### --max_requests_before_restart
|
||||
- **Default:** `None`
|
||||
- **Type:** `int`
|
||||
- Restart worker after this many requests. This is useful for mitigating memory growth over time.
|
||||
- For uvicorn: maps to `limit_max_requests`
|
||||
- For gunicorn: maps to `max_requests`
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --max_requests_before_restart 10000
|
||||
```
|
||||
- **Usage - set Environment Variable:** `MAX_REQUESTS_BEFORE_RESTART`
|
||||
```shell
|
||||
export MAX_REQUESTS_BEFORE_RESTART=10000
|
||||
litellm
|
||||
```
|
||||
|
||||
## Server Backend Options
|
||||
|
||||
### --run_gunicorn
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Starts proxy via gunicorn instead of uvicorn. Better for managing multiple workers in production.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --run_gunicorn
|
||||
```
|
||||
|
||||
### --run_hypercorn
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Starts proxy via hypercorn instead of uvicorn. Supports HTTP/2.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --run_hypercorn
|
||||
```
|
||||
|
||||
### --skip_server_startup
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Skip starting the server after setup (useful for database migrations only).
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --skip_server_startup
|
||||
```
|
||||
|
||||
## SSL/TLS Configuration
|
||||
|
||||
### --ssl_keyfile_path
|
||||
- **Default:** `None`
|
||||
- **Type:** `str`
|
||||
- Path to the SSL keyfile. Use this when you want to provide SSL certificate when starting proxy.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --ssl_keyfile_path /path/to/key.pem --ssl_certfile_path /path/to/cert.pem
|
||||
```
|
||||
- **Usage - set Environment Variable:** `SSL_KEYFILE_PATH`
|
||||
```shell
|
||||
export SSL_KEYFILE_PATH=/path/to/key.pem
|
||||
litellm
|
||||
```
|
||||
|
||||
### --ssl_certfile_path
|
||||
- **Default:** `None`
|
||||
- **Type:** `str`
|
||||
- Path to the SSL certfile. Use this when you want to provide SSL certificate when starting proxy.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --ssl_certfile_path /path/to/cert.pem --ssl_keyfile_path /path/to/key.pem
|
||||
```
|
||||
- **Usage - set Environment Variable:** `SSL_CERTFILE_PATH`
|
||||
```shell
|
||||
export SSL_CERTFILE_PATH=/path/to/cert.pem
|
||||
litellm
|
||||
```
|
||||
|
||||
### --ciphers
|
||||
- **Default:** `None`
|
||||
- **Type:** `str`
|
||||
- Ciphers to use for the SSL setup. Only used with `--run_hypercorn`.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --run_hypercorn --ssl_keyfile_path /path/to/key.pem --ssl_certfile_path /path/to/cert.pem --ciphers "ECDHE+AESGCM"
|
||||
```
|
||||
|
||||
## Model Configuration
|
||||
|
||||
### --model or -m
|
||||
- **Default:** `None`
|
||||
- The model name to pass to LiteLLM.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --model gpt-3.5-turbo
|
||||
```
|
||||
|
||||
### --alias
|
||||
- **Default:** `None`
|
||||
- An alias for the model, for user-friendly reference. Use this to give a litellm model name (e.g., "huggingface/codellama/CodeLlama-7b-Instruct-hf") a more user-friendly name ("codellama").
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --alias my-gpt-model
|
||||
```
|
||||
|
||||
### --api_base
|
||||
- **Default:** `None`
|
||||
- The API base for the model LiteLLM should call.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --model huggingface/tinyllama --api_base https://k58ory32yinf1ly0.us-east-1.aws.endpoints.huggingface.cloud
|
||||
```
|
||||
|
||||
## --api_version
|
||||
- **Default:** `None`
|
||||
### --api_version
|
||||
- **Default:** `2024-07-01-preview`
|
||||
- For Azure services, specify the API version.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --model azure/gpt-deployment --api_version 2023-08-01 --api_base https://<your api base>"
|
||||
```
|
||||
|
||||
## --model or -m
|
||||
### --headers
|
||||
- **Default:** `None`
|
||||
- The model name to pass to Litellm.
|
||||
- Headers for the API call (as JSON string).
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --model gpt-3.5-turbo
|
||||
litellm --model my-model --headers '{"Authorization": "Bearer token"}'
|
||||
```
|
||||
|
||||
## --test
|
||||
- **Type:** `bool` (Flag)
|
||||
- Proxy chat completions URL to make a test request.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --test
|
||||
```
|
||||
|
||||
## --health
|
||||
- **Type:** `bool` (Flag)
|
||||
- Runs a health check on all models in config.yaml
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --health
|
||||
```
|
||||
|
||||
## --alias
|
||||
### --add_key
|
||||
- **Default:** `None`
|
||||
- An alias for the model, for user-friendly reference.
|
||||
- Add a key to the model configuration.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --alias my-gpt-model
|
||||
litellm --add_key my-api-key
|
||||
```
|
||||
|
||||
## --debug
|
||||
### --save
|
||||
- **Type:** `bool` (Flag)
|
||||
- Save the model-specific config.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --model gpt-3.5-turbo --save
|
||||
```
|
||||
|
||||
## Model Parameters
|
||||
|
||||
### --temperature
|
||||
- **Default:** `None`
|
||||
- **Type:** `float`
|
||||
- Set the temperature for the model.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --temperature 0.7
|
||||
```
|
||||
|
||||
### --max_tokens
|
||||
- **Default:** `None`
|
||||
- **Type:** `int`
|
||||
- Set the maximum number of tokens for the model output.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --max_tokens 50
|
||||
```
|
||||
|
||||
### --request_timeout
|
||||
- **Default:** `None`
|
||||
- **Type:** `int`
|
||||
- Set the timeout in seconds for completion calls.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --request_timeout 300
|
||||
```
|
||||
|
||||
### --max_budget
|
||||
- **Default:** `None`
|
||||
- **Type:** `float`
|
||||
- Set max budget for API calls. Works for hosted models like OpenAI, TogetherAI, Anthropic, etc.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --max_budget 100.0
|
||||
```
|
||||
|
||||
### --drop_params
|
||||
- **Type:** `bool` (Flag)
|
||||
- Drop any unmapped params.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --drop_params
|
||||
```
|
||||
|
||||
### --add_function_to_prompt
|
||||
- **Type:** `bool` (Flag)
|
||||
- If a function passed but unsupported, pass it as a part of the prompt.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --add_function_to_prompt
|
||||
```
|
||||
|
||||
## Database Configuration
|
||||
|
||||
### --iam_token_db_auth
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Connects to an RDS database using IAM token authentication instead of a password. This is useful for AWS RDS instances that are configured to use IAM database authentication.
|
||||
- When enabled, LiteLLM will generate an IAM authentication token to connect to the database.
|
||||
- **Required Environment Variables:**
|
||||
- `DATABASE_HOST` - The RDS database host
|
||||
- `DATABASE_PORT` - The database port
|
||||
- `DATABASE_USER` - The database user
|
||||
- `DATABASE_NAME` - The database name
|
||||
- `DATABASE_SCHEMA` (optional) - The database schema
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --iam_token_db_auth
|
||||
```
|
||||
- **Usage - set Environment Variable:** `IAM_TOKEN_DB_AUTH`
|
||||
```shell
|
||||
export IAM_TOKEN_DB_AUTH=True
|
||||
export DATABASE_HOST=mydb.us-east-1.rds.amazonaws.com
|
||||
export DATABASE_PORT=5432
|
||||
export DATABASE_USER=mydbuser
|
||||
export DATABASE_NAME=mydb
|
||||
litellm
|
||||
```
|
||||
|
||||
### --use_prisma_db_push
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Use `prisma db push` instead of `prisma migrate` for database schema updates. This is useful when you want to quickly sync your database schema without creating migration files.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --use_prisma_db_push
|
||||
```
|
||||
|
||||
## Debugging
|
||||
|
||||
### --debug
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Enable debugging mode for the input.
|
||||
|
|
@ -102,10 +323,10 @@ Cli arguments, --host, --port, --num_workers
|
|||
litellm
|
||||
```
|
||||
|
||||
## --detailed_debug
|
||||
### --detailed_debug
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Enable debugging mode for the input.
|
||||
- Enable detailed debugging mode to view verbose debug logs.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --detailed_debug
|
||||
|
|
@ -116,80 +337,76 @@ Cli arguments, --host, --port, --num_workers
|
|||
litellm
|
||||
```
|
||||
|
||||
#### --temperature
|
||||
- **Default:** `None`
|
||||
- **Type:** `float`
|
||||
- Set the temperature for the model.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --temperature 0.7
|
||||
```
|
||||
|
||||
## --max_tokens
|
||||
- **Default:** `None`
|
||||
- **Type:** `int`
|
||||
- Set the maximum number of tokens for the model output.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --max_tokens 50
|
||||
```
|
||||
|
||||
## --request_timeout
|
||||
- **Default:** `6000`
|
||||
- **Type:** `int`
|
||||
- Set the timeout in seconds for completion calls.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --request_timeout 300
|
||||
```
|
||||
|
||||
## --drop_params
|
||||
### --local
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Drop any unmapped params.
|
||||
- For local debugging purposes.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --drop_params
|
||||
litellm --local
|
||||
```
|
||||
|
||||
## --add_function_to_prompt
|
||||
## Testing & Health Checks
|
||||
|
||||
### --test
|
||||
- **Type:** `bool` (Flag)
|
||||
- If a function passed but unsupported, pass it as a part of the prompt.
|
||||
- Proxy chat completions URL to make a test request to.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --add_function_to_prompt
|
||||
litellm --test
|
||||
```
|
||||
|
||||
## --config
|
||||
- Configure Litellm by providing a configuration file path.
|
||||
### --test_async
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Calls async endpoints `/queue/requests` and `/queue/response`.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --config path/to/config.yaml
|
||||
litellm --test_async
|
||||
```
|
||||
|
||||
## --telemetry
|
||||
### --num_requests
|
||||
- **Default:** `10`
|
||||
- **Type:** `int`
|
||||
- Number of requests to hit async endpoint with (used with `--test_async`).
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --test_async --num_requests 100
|
||||
```
|
||||
|
||||
### --health
|
||||
- **Type:** `bool` (Flag)
|
||||
- Runs a health check on all models in config.yaml.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --health
|
||||
```
|
||||
|
||||
## Other Options
|
||||
|
||||
### --version
|
||||
- **Short form:** `-v`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Print LiteLLM version and exit.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --version
|
||||
```
|
||||
|
||||
### --telemetry
|
||||
- **Default:** `True`
|
||||
- **Type:** `bool`
|
||||
- Help track usage of this feature.
|
||||
- Help track usage of this feature. Turn off for privacy.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --telemetry False
|
||||
```
|
||||
|
||||
|
||||
## --log_config
|
||||
- **Default:** `None`
|
||||
- **Type:** `str`
|
||||
- Specify a log configuration file for uvicorn.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --log_config path/to/log_config.conf
|
||||
```
|
||||
|
||||
## --skip_server_startup
|
||||
### --use_queue
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Skip starting the server after setup (useful for DB migrations only).
|
||||
- To use celery workers for async endpoints.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --skip_server_startup
|
||||
```
|
||||
litellm --use_queue
|
||||
```
|
||||
|
|
|
|||
|
|
@ -94,7 +94,7 @@ litellm_settings:
|
|||
# /chat/completions, /completions, /embeddings, /audio/transcriptions
|
||||
mode: default_off # if default_off, you need to opt in to caching on a per call basis
|
||||
ttl: 600 # ttl for caching
|
||||
disable_copilot_system_to_assistant: False # If false (default), converts all 'system' role messages to 'assistant' for GitHub Copilot compatibility. Set to true to disable this behavior.
|
||||
disable_copilot_system_to_assistant: False # DEPRECATED - GitHub Copilot API supports system prompts.
|
||||
|
||||
callback_settings:
|
||||
otel:
|
||||
|
|
@ -197,7 +197,7 @@ router_settings:
|
|||
| disable_add_transform_inline_image_block | boolean | For Fireworks AI models - if true, turns off the auto-add of `#transform=inline` to the url of the image_url, if the model is not a vision model. |
|
||||
| disable_hf_tokenizer_download | boolean | If true, it defaults to using the openai tokenizer for all models (including huggingface models). |
|
||||
| enable_json_schema_validation | boolean | If true, enables json schema validation for all requests. |
|
||||
| disable_copilot_system_to_assistant | boolean | If false (default), converts all 'system' role messages to 'assistant' for GitHub Copilot compatibility. Set to true to disable this behavior. Useful for tools (like Claude Code) that send system messages, which Copilot does not support. |
|
||||
| disable_copilot_system_to_assistant | boolean | **DEPRECATED** - GitHub Copilot API supports system prompts. |
|
||||
|
||||
### general_settings - Reference
|
||||
|
||||
|
|
@ -395,7 +395,7 @@ router_settings:
|
|||
| ATHINA_API_KEY | API key for Athina service
|
||||
| ATHINA_BASE_URL | Base URL for Athina service (defaults to `https://log.athina.ai`)
|
||||
| AUTH_STRATEGY | Strategy used for authentication (e.g., OAuth, API key)
|
||||
| AUTO_REDIRECT_UI_LOGIN_TO_SSO | Flag to enable automatic redirect of UI login page to SSO when SSO is configured. Default is **true**
|
||||
| AUTO_REDIRECT_UI_LOGIN_TO_SSO | Flag to enable automatic redirect of UI login page to SSO when SSO is configured. Default is **false**
|
||||
| AUDIO_SPEECH_CHUNK_SIZE | Chunk size for audio speech processing. Default is 1024
|
||||
| ANTHROPIC_API_KEY | API key for Anthropic service
|
||||
| ANTHROPIC_API_BASE | Base URL for Anthropic API. Default is https://api.anthropic.com
|
||||
|
|
@ -520,6 +520,7 @@ router_settings:
|
|||
| DEBUG_OTEL | Enable debug mode for OpenTelemetry
|
||||
| DEFAULT_ALLOWED_FAILS | Maximum failures allowed before cooling down a model. Default is 3
|
||||
| DEFAULT_A2A_AGENT_TIMEOUT | Default timeout in seconds for A2A (Agent-to-Agent) protocol requests. Default is 6000
|
||||
| DEFAULT_ACCESS_GROUP_CACHE_TTL | Time-to-live in seconds for cached access group information. Default is 600 (10 minutes)
|
||||
| DEFAULT_ANTHROPIC_CHAT_MAX_TOKENS | Default maximum tokens for Anthropic chat completions. Default is 4096
|
||||
| DEFAULT_BATCH_SIZE | Default batch size for operations. Default is 512
|
||||
| DEFAULT_CHUNK_OVERLAP | Default chunk overlap for RAG text splitters. Default is 200
|
||||
|
|
@ -548,10 +549,15 @@ router_settings:
|
|||
| DEFAULT_MCP_SEMANTIC_FILTER_EMBEDDING_MODEL | Default embedding model for MCP semantic tool filtering. Default is "text-embedding-3-small"
|
||||
| DEFAULT_MCP_SEMANTIC_FILTER_SIMILARITY_THRESHOLD | Default similarity threshold for MCP semantic tool filtering. Default is 0.3
|
||||
| DEFAULT_MCP_SEMANTIC_FILTER_TOP_K | Default number of top results to return for MCP semantic tool filtering. Default is 10
|
||||
| MCP_NPM_CACHE_DIR | Directory for npm cache used by STDIO MCP servers. In containers the default (~/.npm) may not exist or be read-only. Default is `/tmp/.npm_mcp_cache`
|
||||
| MCP_OAUTH2_TOKEN_CACHE_DEFAULT_TTL | Default TTL in seconds for MCP OAuth2 token cache. Default is 3600
|
||||
| MCP_OAUTH2_TOKEN_CACHE_MAX_SIZE | Maximum number of entries in MCP OAuth2 token cache. Default is 200
|
||||
| MCP_OAUTH2_TOKEN_CACHE_MIN_TTL | Minimum TTL in seconds for MCP OAuth2 token cache. Default is 10
|
||||
| MCP_OAUTH2_TOKEN_EXPIRY_BUFFER_SECONDS | Seconds to subtract from token expiry when computing cache TTL. Default is 60
|
||||
| DEFAULT_MOCK_RESPONSE_COMPLETION_TOKEN_COUNT | Default token count for mock response completions. Default is 20
|
||||
| DEFAULT_MOCK_RESPONSE_PROMPT_TOKEN_COUNT | Default token count for mock response prompts. Default is 10
|
||||
| DEFAULT_MODEL_CREATED_AT_TIME | Default creation timestamp for models. Default is 1677610602
|
||||
| DEFAULT_NUM_WORKERS_LITELLM_PROXY | Default number of workers for LiteLLM proxy. Default is 4. **We strongly recommend setting NUM Workers to Number of vCPUs available**
|
||||
| DEFAULT_NUM_WORKERS_LITELLM_PROXY | Default number of workers for LiteLLM proxy when `NUM_WORKERS` is not set. Default is 1. **We strongly recommend setting NUM_WORKERS to the number of vCPUs available** (e.g. `NUM_WORKERS=8` or `--num_workers 8`).
|
||||
| DEFAULT_PROMPT_INJECTION_SIMILARITY_THRESHOLD | Default threshold for prompt injection similarity. Default is 0.7
|
||||
| DEFAULT_POLLING_INTERVAL | Default polling interval for schedulers in seconds. Default is 0.03
|
||||
| DEFAULT_REASONING_EFFORT_DISABLE_THINKING_BUDGET | Default reasoning effort disable thinking budget. Default is 0
|
||||
|
|
@ -640,6 +646,7 @@ router_settings:
|
|||
| GENERIC_TOKEN_ENDPOINT | Token endpoint for generic OAuth providers
|
||||
| GENERIC_USER_DISPLAY_NAME_ATTRIBUTE | Attribute for user's display name in generic auth
|
||||
| GENERIC_USER_EMAIL_ATTRIBUTE | Attribute for user's email in generic auth
|
||||
| GENERIC_USER_EXTRA_ATTRIBUTES | Comma-separated list of additional fields to extract from generic SSO provider response (e.g., "department,employee_id,groups"). Accessible via `CustomOpenID.extra_fields` in custom SSO handlers. Supports dot notation for nested fields
|
||||
| GENERIC_USER_FIRST_NAME_ATTRIBUTE | Attribute for user's first name in generic auth
|
||||
| GENERIC_USER_ID_ATTRIBUTE | Attribute for user ID in generic auth
|
||||
| GENERIC_USER_LAST_NAME_ATTRIBUTE | Attribute for user's last name in generic auth
|
||||
|
|
@ -740,9 +747,12 @@ router_settings:
|
|||
| LITERAL_API_KEY | API key for Literal integration
|
||||
| LITERAL_API_URL | API URL for Literal service
|
||||
| LITERAL_BATCH_SIZE | Batch size for Literal operations
|
||||
| LITELLM_ANTHROPIC_BETA_HEADERS_URL | Custom URL for fetching Anthropic beta headers configuration. Default is the GitHub main branch URL
|
||||
| LITELLM_ANTHROPIC_DISABLE_URL_SUFFIX | Disable automatic URL suffix appending for Anthropic API base URLs. When set to `true`, prevents LiteLLM from automatically adding `/v1/messages` or `/v1/complete` to custom Anthropic API endpoints
|
||||
| LITELLM_ASSETS_PATH | Path to directory for UI assets and logos. Used when running with read-only filesystem (e.g., Kubernetes). Default is `/var/lib/litellm/assets` in Docker.
|
||||
| LITELLM_CLI_JWT_EXPIRATION_HOURS | Expiration time in hours for CLI-generated JWT tokens. Default is 24 hours
|
||||
| LITELLM_DD_AGENT_HOST | Hostname or IP of DataDog agent for LiteLLM-specific logging. When set, logs are sent to agent instead of direct API
|
||||
| LITELLM_DEPLOYMENT_ENVIRONMENT | Environment name for the deployment (e.g., "production", "staging"). Used as a fallback when OTEL_ENVIRONMENT_NAME is not set. Sets the `environment` tag in telemetry data
|
||||
| LITELLM_DD_AGENT_PORT | Port of DataDog agent for LiteLLM-specific log intake. Default is 10518
|
||||
| LITELLM_DD_LLM_OBS_PORT | Port for Datadog LLM Observability agent. Default is 8126
|
||||
| LITELLM_DONT_SHOW_FEEDBACK_BOX | Flag to hide feedback box in LiteLLM UI
|
||||
|
|
@ -755,11 +765,14 @@ router_settings:
|
|||
| LITELLM_MIGRATION_DIR | Custom migrations directory for prisma migrations, used for baselining db in read-only file systems.
|
||||
| LITELLM_HOSTED_UI | URL of the hosted UI for LiteLLM
|
||||
| LITELLM_UI_API_DOC_BASE_URL | Optional override for the API Reference base URL (used in sample code/docs) when the admin UI runs on a different host than the proxy. Defaults to `PROXY_BASE_URL` when unset.
|
||||
| LITELLM_UI_PATH | Path to directory for Admin UI files. Used when running with read-only filesystem (e.g., Kubernetes). Default is `/var/lib/litellm/ui` in Docker.
|
||||
| LITELM_ENVIRONMENT | Environment of LiteLLM Instance, used by logging services. Currently only used by DeepEval.
|
||||
| LITELLM_KEY_ROTATION_ENABLED | Enable auto-key rotation for LiteLLM (boolean). Default is false.
|
||||
| LITELLM_KEY_ROTATION_CHECK_INTERVAL_SECONDS | Interval in seconds for how often to run job that auto-rotates keys. Default is 86400 (24 hours).
|
||||
| LITELLM_LICENSE | License key for LiteLLM usage
|
||||
| LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS | Set to `True` to use the local bundled Anthropic beta headers config only, disabling remote fetching. Default is `False`
|
||||
| LITELLM_LOCAL_MODEL_COST_MAP | Local configuration for model cost mapping in LiteLLM
|
||||
| LITELLM_LOCAL_POLICY_TEMPLATES | When set to "true", uses local backup policy templates instead of fetching from GitHub. Policy templates are fetched from https://raw.githubusercontent.com/BerriAI/litellm/main/policy_templates.json by default, with automatic fallback to local backup on failure
|
||||
| LITELLM_LOG | Enable detailed logging for LiteLLM
|
||||
| LITELLM_MODEL_COST_MAP_URL | URL for fetching model cost map data. Default is https://raw.githubusercontent.com/BerriAI/litellm/main/model_prices_and_context_window.json
|
||||
| LITELLM_LOG_FILE | File path to write LiteLLM logs to. When set, logs will be written to both console and the specified file
|
||||
|
|
@ -767,6 +780,10 @@ router_settings:
|
|||
| LITELLM_METER_NAME | Name for OTEL Meter
|
||||
| LITELLM_OTEL_INTEGRATION_ENABLE_EVENTS | Optionally enable semantic logs for OTEL
|
||||
| LITELLM_OTEL_INTEGRATION_ENABLE_METRICS | Optionally enable emantic metrics for OTEL
|
||||
| LITELLM_ENABLE_PYROSCOPE | If true, enables Pyroscope CPU profiling. Profiles are sent to PYROSCOPE_SERVER_ADDRESS. Off by default. See [Pyroscope profiling](/proxy/pyroscope_profiling).
|
||||
| PYROSCOPE_APP_NAME | Application name reported to Pyroscope. Required when LITELLM_ENABLE_PYROSCOPE is true. No default.
|
||||
| PYROSCOPE_SERVER_ADDRESS | Pyroscope server URL to send profiles to. Required when LITELLM_ENABLE_PYROSCOPE is true. No default.
|
||||
| PYROSCOPE_SAMPLE_RATE | Optional. Sample rate for Pyroscope profiling (integer). No default; when unset, the pyroscope-io library default is used.
|
||||
| LITELLM_MASTER_KEY | Master key for proxy authentication
|
||||
| LITELLM_MODE | Operating mode for LiteLLM (e.g., production, development)
|
||||
| LITELLM_NON_ROOT | Flag to run LiteLLM in non-root mode for enhanced security in Docker containers
|
||||
|
|
@ -779,6 +796,7 @@ router_settings:
|
|||
| LITELLM_USER_AGENT | Custom user agent string for LiteLLM API requests. Used for partner telemetry attribution
|
||||
| LITELLM_PRINT_STANDARD_LOGGING_PAYLOAD | If true, prints the standard logging payload to the console - useful for debugging
|
||||
| LITELM_ENVIRONMENT | Environment for LiteLLM Instance. This is currently only logged to DeepEval to determine the environment for DeepEval integration.
|
||||
| LITELLM_ASYNCIO_QUEUE_MAXSIZE | Maximum size for asyncio queues (e.g. log queues, spend update queues, and cookbook examples such as realtime audio in `nova_sonic_realtime.py`). Bounds in-memory growth to prevent OOM. Default is 1000.
|
||||
| LOGFIRE_TOKEN | Token for Logfire logging service
|
||||
| LOGFIRE_BASE_URL | Base URL for Logfire logging service (useful for self hosted deployments)
|
||||
| LOGGING_WORKER_CONCURRENCY | Maximum number of concurrent coroutine slots for the logging worker on the asyncio event loop. Default is 100. Setting too high will flood the event loop with logging tasks which will lower the overall latency of the requests.
|
||||
|
|
@ -806,6 +824,7 @@ router_settings:
|
|||
| MAX_RETRY_DELAY | Maximum delay in seconds for retrying requests. Default is 8.0
|
||||
| MAX_LANGFUSE_INITIALIZED_CLIENTS | Maximum number of Langfuse clients to initialize on proxy. Default is 50. This is set since langfuse initializes 1 thread everytime a client is initialized. We've had an incident in the past where we reached 100% cpu utilization because Langfuse was initialized several times.
|
||||
| MAX_MCP_SEMANTIC_FILTER_TOOLS_HEADER_LENGTH | Maximum header length for MCP semantic filter tools. Default is 150
|
||||
| MAX_POLICY_ESTIMATE_IMPACT_ROWS | Maximum number of rows returned when estimating the impact of a policy. Default is 1000
|
||||
| MIN_NON_ZERO_TEMPERATURE | Minimum non-zero temperature value. Default is 0.0001
|
||||
| MINIMUM_PROMPT_CACHE_TOKEN_COUNT | Minimum token count for caching a prompt. Default is 1024
|
||||
| MISTRAL_API_BASE | Base URL for Mistral API. Default is https://api.mistral.ai
|
||||
|
|
@ -822,6 +841,8 @@ router_settings:
|
|||
| MICROSOFT_USER_ID_ATTRIBUTE | Field name for user ID in Microsoft SSO response. Default is `id`
|
||||
| MICROSOFT_USER_LAST_NAME_ATTRIBUTE | Field name for user last name in Microsoft SSO response. Default is `surname`
|
||||
| MICROSOFT_USERINFO_ENDPOINT | Custom userinfo endpoint URL for Microsoft SSO (overrides default Microsoft Graph userinfo endpoint)
|
||||
| MODEL_COST_MAP_MAX_SHRINK_RATIO | Maximum allowed shrinkage ratio when validating a fetched model cost map against the local backup. Rejects the fetched map if it is smaller than this fraction of the backup. Default is 0.5
|
||||
| MODEL_COST_MAP_MIN_MODEL_COUNT | Minimum number of models a fetched cost map must contain to be considered valid. Default is 50
|
||||
| NO_DOCS | Flag to disable Swagger UI documentation
|
||||
| NO_REDOC | Flag to disable Redoc documentation
|
||||
| NO_PROXY | List of addresses to bypass proxy
|
||||
|
|
|
|||
|
|
@ -469,6 +469,7 @@ credential_list:
|
|||
api_version: "2023-05-15"
|
||||
credential_info:
|
||||
description: "Production credentials for EU region"
|
||||
custom_llm_provider: "azure"
|
||||
```
|
||||
|
||||
#### Key Parameters
|
||||
|
|
|
|||
|
|
@ -142,6 +142,18 @@ async def custom_sso_handler(userIDPInfo: OpenID) -> SSOUserDefinedValues:
|
|||
f"No ID found for user. userIDPInfo.id is None {userIDPInfo}"
|
||||
)
|
||||
|
||||
#################################################
|
||||
# Access extra fields from SSO provider (requires GENERIC_USER_EXTRA_ATTRIBUTES env var)
|
||||
# Example: Set GENERIC_USER_EXTRA_ATTRIBUTES="department,employee_id,groups"
|
||||
extra_fields = getattr(userIDPInfo, 'extra_fields', None) or {}
|
||||
user_department = extra_fields.get("department")
|
||||
employee_id = extra_fields.get("employee_id")
|
||||
user_groups = extra_fields.get("groups", [])
|
||||
|
||||
print(f"User department: {user_department}") # noqa
|
||||
print(f"Employee ID: {employee_id}") # noqa
|
||||
print(f"User groups: {user_groups}") # noqa
|
||||
#################################################
|
||||
|
||||
#################################################
|
||||
# Run your custom code / logic here
|
||||
|
|
|
|||
|
|
@ -6,6 +6,52 @@ Control which model groups can forward client headers to the underlying LLM prov
|
|||
|
||||
By default, LiteLLM does not forward client headers to LLM provider APIs for security reasons. However, you can selectively enable header forwarding for specific model groups using the `forward_client_headers_to_llm_api` setting.
|
||||
|
||||
## How it Works
|
||||
|
||||
LiteLLM does **not** forward all client headers to the LLM provider. Instead, it uses an **allowlist** approach — only headers matching specific rules are forwarded. This ensures sensitive headers (like your LiteLLM API key) are never accidentally sent to upstream providers.
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant Client as Client (SDK / curl)
|
||||
participant Proxy as LiteLLM Proxy
|
||||
participant Filter as Header Filter (Allowlist)
|
||||
participant LLM as LLM Provider (OpenAI, Anthropic, etc.)
|
||||
|
||||
Client->>Proxy: Request with all headers<br/>(Authorization, x-trace-id,<br/>x-custom-header, anthropic-beta, etc.)
|
||||
|
||||
Proxy->>Filter: Check forward_client_headers_to_llm_api<br/>setting for this model group
|
||||
|
||||
Note over Filter: Allowlist rules:<br/>1. Headers starting with "x-" ✅<br/>2. "anthropic-beta" ✅<br/>3. "x-stainless-*" ❌ (blocked)<br/>4. All other headers ❌ (blocked)
|
||||
|
||||
Filter-->>Proxy: Return only allowed headers
|
||||
|
||||
Proxy->>LLM: Request with filtered headers<br/>(x-trace-id, x-custom-header,<br/>anthropic-beta)
|
||||
|
||||
LLM-->>Proxy: Response
|
||||
Proxy-->>Client: Response
|
||||
```
|
||||
|
||||
### Header Allowlist Rules
|
||||
|
||||
The following rules determine which headers are forwarded (see [`_get_forwardable_headers`](https://github.com/litellm/litellm/blob/main/litellm/proxy/litellm_pre_call_utils.py) in `litellm/proxy/litellm_pre_call_utils.py`):
|
||||
|
||||
| Rule | Example | Forwarded? |
|
||||
|---|---|---|
|
||||
| Headers starting with `x-` | `x-trace-id`, `x-custom-header`, `x-request-source` | ✅ Yes |
|
||||
| `anthropic-beta` header | `anthropic-beta: prompt-caching-2024-07-31` | ✅ Yes |
|
||||
| Headers starting with `x-stainless-*` | `x-stainless-lang`, `x-stainless-arch` | ❌ No (causes OpenAI SDK issues) |
|
||||
| Standard HTTP headers | `Authorization`, `Content-Type`, `Host` | ❌ No |
|
||||
| Other provider headers | `Accept`, `User-Agent` | ❌ No |
|
||||
|
||||
### Additional Header Mechanisms
|
||||
|
||||
| Mechanism | Description | Reference |
|
||||
|---|---|---|
|
||||
| **`x-pass-` prefix** | Headers prefixed with `x-pass-` are always forwarded with the prefix stripped, regardless of settings. E.g., `x-pass-anthropic-beta: value` → `anthropic-beta: value`. Works for all pass-through endpoints. | [Source code](https://github.com/litellm/litellm/blob/main/litellm/passthrough/utils.py) |
|
||||
| **`openai-organization`** | Forwarded only when `forward_openai_org_id: true` is set in `general_settings`. | [Forward OpenAI Org ID](#enable-globally) |
|
||||
| **User information headers** | When `add_user_information_to_llm_headers: true`, LiteLLM adds `x-litellm-user-id`, `x-litellm-org-id`, etc. | [User Information Headers](#user-information-headers-optional) |
|
||||
| **Vertex AI pass-through** | Uses a separate, stricter allowlist: only `anthropic-beta` and `content-type`. | [Source code](https://github.com/litellm/litellm/blob/main/litellm/constants.py) |
|
||||
|
||||
## Configuration
|
||||
|
||||
## Enable Globally
|
||||
|
|
|
|||
332
docs/my-website/docs/proxy/guardrails/custom_code_guardrail.md
Normal file
|
|
@ -0,0 +1,332 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Custom Code Guardrail
|
||||
|
||||
Write custom guardrail logic using Python-like code that runs in a sandboxed environment.
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Define the guardrail in config
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
guardrails:
|
||||
- guardrail_name: block-ssn
|
||||
litellm_params:
|
||||
guardrail: custom_code
|
||||
mode: pre_call
|
||||
custom_code: |
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
for text in inputs["texts"]:
|
||||
if regex_match(text, r"\d{3}-\d{2}-\d{4}"):
|
||||
return block("SSN detected")
|
||||
return allow()
|
||||
```
|
||||
|
||||
### 2. Start proxy
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
### 3. Test
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/chat/completions \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "gpt-4",
|
||||
"messages": [{"role": "user", "content": "My SSN is 123-45-6789"}],
|
||||
"guardrails": ["block-ssn"]
|
||||
}'
|
||||
```
|
||||
|
||||
## Configuration
|
||||
|
||||
| Parameter | Type | Required | Description |
|
||||
|-----------|------|----------|-------------|
|
||||
| `guardrail` | string | ✅ | Must be `custom_code` |
|
||||
| `mode` | string | ✅ | When to run: `pre_call`, `post_call`, `during_call` |
|
||||
| `custom_code` | string | ✅ | Python-like code with `apply_guardrail` function |
|
||||
| `default_on` | bool | ❌ | Run on all requests (default: `false`) |
|
||||
|
||||
## Writing Custom Code
|
||||
|
||||
### Function Signature
|
||||
|
||||
Your code must define an `apply_guardrail` function. It can be either sync or async:
|
||||
|
||||
```python
|
||||
# Sync version
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
# inputs: see table below
|
||||
# request_data: {"model": "...", "user_id": "...", "team_id": "...", "metadata": {...}}
|
||||
# input_type: "request" or "response"
|
||||
|
||||
return allow() # or block() or modify()
|
||||
|
||||
# Async version (recommended when using HTTP primitives)
|
||||
async def apply_guardrail(inputs, request_data, input_type):
|
||||
response = await http_post("https://api.example.com/check", body={"text": inputs["texts"][0]})
|
||||
if response["success"] and response["body"].get("flagged"):
|
||||
return block("Content flagged")
|
||||
return allow()
|
||||
```
|
||||
|
||||
### `inputs` Parameter
|
||||
|
||||
| Field | Type | Description |
|
||||
|-------|------|-------------|
|
||||
| `texts` | `List[str]` | Extracted text from the request/response |
|
||||
| `images` | `List[str]` | Extracted images (for image guardrails) |
|
||||
| `tools` | `List[dict]` | Tools sent to the LLM |
|
||||
| `tool_calls` | `List[dict]` | Tool calls returned from the LLM |
|
||||
| `structured_messages` | `List[dict]` | Full messages with role info (system/user/assistant) |
|
||||
| `model` | `str` | The model being used |
|
||||
|
||||
### `request_data` Parameter
|
||||
|
||||
| Field | Type | Description |
|
||||
|-------|------|-------------|
|
||||
| `model` | `str` | Model name |
|
||||
| `user_id` | `str` | User ID from API key |
|
||||
| `team_id` | `str` | Team ID from API key |
|
||||
| `end_user_id` | `str` | End user ID |
|
||||
| `metadata` | `dict` | Request metadata |
|
||||
|
||||
### Return Values
|
||||
|
||||
| Function | Description |
|
||||
|----------|-------------|
|
||||
| `allow()` | Let request/response through |
|
||||
| `block(reason)` | Reject with message |
|
||||
| `modify(texts=[], images=[], tool_calls=[])` | Transform content |
|
||||
|
||||
## Built-in Primitives
|
||||
|
||||
### Regex
|
||||
|
||||
| Function | Description |
|
||||
|----------|-------------|
|
||||
| `regex_match(text, pattern)` | Returns `True` if pattern found |
|
||||
| `regex_replace(text, pattern, replacement)` | Replace all matches |
|
||||
| `regex_find_all(text, pattern)` | Return list of matches |
|
||||
|
||||
### JSON
|
||||
|
||||
| Function | Description |
|
||||
|----------|-------------|
|
||||
| `json_parse(text)` | Parse JSON string, returns `None` on error |
|
||||
| `json_stringify(obj)` | Convert to JSON string |
|
||||
| `json_schema_valid(obj, schema)` | Validate against JSON schema |
|
||||
|
||||
### URL
|
||||
|
||||
| Function | Description |
|
||||
|----------|-------------|
|
||||
| `extract_urls(text)` | Extract all URLs from text |
|
||||
| `is_valid_url(url)` | Check if URL is valid |
|
||||
| `all_urls_valid(text)` | Check all URLs in text are valid |
|
||||
|
||||
### Code Detection
|
||||
|
||||
| Function | Description |
|
||||
|----------|-------------|
|
||||
| `detect_code(text)` | Returns `True` if code detected |
|
||||
| `detect_code_languages(text)` | Returns list of detected languages |
|
||||
| `contains_code_language(text, ["sql", "python"])` | Check for specific languages |
|
||||
|
||||
### Text Utilities
|
||||
|
||||
| Function | Description |
|
||||
|----------|-------------|
|
||||
| `contains(text, substring)` | Check if substring exists |
|
||||
| `contains_any(text, [substr1, substr2])` | Check if any substring exists |
|
||||
| `word_count(text)` | Count words |
|
||||
| `char_count(text)` | Count characters |
|
||||
| `lower(text)` / `upper(text)` / `trim(text)` | String transforms |
|
||||
|
||||
### HTTP Requests (Async)
|
||||
|
||||
Make async HTTP requests to external APIs for additional validation or content moderation.
|
||||
|
||||
| Function | Description |
|
||||
|----------|-------------|
|
||||
| `await http_request(url, method, headers, body, timeout)` | General async HTTP request |
|
||||
| `await http_get(url, headers, timeout)` | Async GET request |
|
||||
| `await http_post(url, body, headers, timeout)` | Async POST request |
|
||||
|
||||
**Response format:**
|
||||
```python
|
||||
{
|
||||
"status_code": 200, # HTTP status code
|
||||
"body": {...}, # Response body (parsed JSON or string)
|
||||
"headers": {...}, # Response headers
|
||||
"success": True, # True if status code is 2xx
|
||||
"error": None # Error message if request failed
|
||||
}
|
||||
```
|
||||
|
||||
**Note:** When using HTTP primitives, define your function as `async def apply_guardrail(...)` for non-blocking execution.
|
||||
|
||||
## Examples
|
||||
|
||||
### Block PII (SSN)
|
||||
|
||||
```python
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
for text in inputs["texts"]:
|
||||
if regex_match(text, r"\d{3}-\d{2}-\d{4}"):
|
||||
return block("SSN detected")
|
||||
return allow()
|
||||
```
|
||||
|
||||
### Redact Email Addresses
|
||||
|
||||
```python
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
pattern = r"[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}"
|
||||
modified = []
|
||||
for text in inputs["texts"]:
|
||||
modified.append(regex_replace(text, pattern, "[EMAIL REDACTED]"))
|
||||
return modify(texts=modified)
|
||||
```
|
||||
|
||||
### Block SQL Injection
|
||||
|
||||
```python
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
if input_type != "request":
|
||||
return allow()
|
||||
for text in inputs["texts"]:
|
||||
if contains_code_language(text, ["sql"]):
|
||||
return block("SQL code not allowed")
|
||||
return allow()
|
||||
```
|
||||
|
||||
### Validate JSON Response
|
||||
|
||||
```python
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
if input_type != "response":
|
||||
return allow()
|
||||
|
||||
schema = {
|
||||
"type": "object",
|
||||
"required": ["name", "value"]
|
||||
}
|
||||
|
||||
for text in inputs["texts"]:
|
||||
obj = json_parse(text)
|
||||
if obj is None:
|
||||
return block("Invalid JSON response")
|
||||
if not json_schema_valid(obj, schema):
|
||||
return block("Response missing required fields")
|
||||
return allow()
|
||||
```
|
||||
|
||||
### Check URLs in Response
|
||||
|
||||
```python
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
if input_type != "response":
|
||||
return allow()
|
||||
for text in inputs["texts"]:
|
||||
if not all_urls_valid(text):
|
||||
return block("Response contains invalid URLs")
|
||||
return allow()
|
||||
```
|
||||
|
||||
### Call External Moderation API (Async)
|
||||
|
||||
```python
|
||||
async def apply_guardrail(inputs, request_data, input_type):
|
||||
# Call an external moderation API
|
||||
for text in inputs["texts"]:
|
||||
response = await http_post(
|
||||
"https://api.example.com/moderate",
|
||||
body={"text": text, "user_id": request_data["user_id"]},
|
||||
headers={"Authorization": "Bearer YOUR_API_KEY"},
|
||||
timeout=10
|
||||
)
|
||||
|
||||
if not response["success"]:
|
||||
# API call failed - decide whether to allow or block
|
||||
return allow()
|
||||
|
||||
if response["body"].get("flagged"):
|
||||
return block(response["body"].get("reason", "Content flagged"))
|
||||
|
||||
return allow()
|
||||
```
|
||||
|
||||
### Combine Multiple Checks
|
||||
|
||||
```python
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
modified = []
|
||||
|
||||
for text in inputs["texts"]:
|
||||
# Redact SSN
|
||||
text = regex_replace(text, r"\d{3}-\d{2}-\d{4}", "[SSN]")
|
||||
# Redact credit cards
|
||||
text = regex_replace(text, r"\d{16}", "[CARD]")
|
||||
modified.append(text)
|
||||
|
||||
# Block SQL in requests
|
||||
if input_type == "request":
|
||||
for text in inputs["texts"]:
|
||||
if contains_code_language(text, ["sql"]):
|
||||
return block("SQL injection blocked")
|
||||
|
||||
return modify(texts=modified)
|
||||
```
|
||||
|
||||
## Sandbox Restrictions
|
||||
|
||||
Custom code runs in a restricted environment:
|
||||
|
||||
- ❌ No `import` statements
|
||||
- ❌ No file I/O
|
||||
- ❌ No `exec()` or `eval()`
|
||||
- ✅ HTTP requests via built-in `http_request`, `http_get`, `http_post` primitives
|
||||
- ✅ Only LiteLLM-provided primitives available
|
||||
|
||||
## Per-Request Usage
|
||||
|
||||
Enable guardrail per request:
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/chat/completions \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "gpt-4",
|
||||
"messages": [{"role": "user", "content": "Hello"}],
|
||||
"guardrails": ["block-ssn"]
|
||||
}'
|
||||
```
|
||||
|
||||
## Default On
|
||||
|
||||
Run guardrail on all requests:
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
guardrails:
|
||||
- guardrail_name: block-ssn
|
||||
litellm_params:
|
||||
guardrail: custom_code
|
||||
mode: pre_call
|
||||
default_on: true
|
||||
custom_code: |
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
...
|
||||
```
|
||||
|
|
@ -13,20 +13,26 @@ Cygnal returns a `violation` score between `0` and `1` (higher means more likely
|
|||
|
||||
### 1. Obtain Credentials
|
||||
|
||||
1. Create a Gray Swan account and generate a Cygnal API key.
|
||||
1. Log in to our Gray Swan platform and generate a Cygnal API key.
|
||||
|
||||
For existing customers, you should already have access to our [platform](https://platform.grayswan.ai).
|
||||
|
||||
For new users, please register at this [page](https://hubs.ly/Q03-sX1J0) and we are more than happy to give you an onboarding!
|
||||
|
||||
|
||||
2. Configure environment variables for the LiteLLM proxy host:
|
||||
|
||||
```bash
|
||||
export GRAYSWAN_API_KEY="your-grayswan-key"
|
||||
export GRAYSWAN_API_BASE="https://api.grayswan.ai"
|
||||
```
|
||||
```bash
|
||||
export GRAYSWAN_API_KEY="your-grayswan-key"
|
||||
export GRAYSWAN_API_BASE="https://api.grayswan.ai"
|
||||
```
|
||||
|
||||
### 2. Configure `config.yaml`
|
||||
|
||||
Add a guardrail entry that references the Gray Swan integration. Below is a balanced example that monitors both input and output but only blocks once the violation score reaches the configured threshold.
|
||||
Add a guardrail entry that references the Gray Swan integration. Below is our recommmended settings.
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
model_list: # this part is a standard litellm configuration for reference
|
||||
- model_name: openai/gpt-4.1-mini
|
||||
litellm_params:
|
||||
model: openai/gpt-4.1-mini
|
||||
|
|
@ -40,13 +46,14 @@ guardrails:
|
|||
api_key: os.environ/GRAYSWAN_API_KEY
|
||||
api_base: os.environ/GRAYSWAN_API_BASE # optional
|
||||
optional_params:
|
||||
on_flagged_action: monitor # or "block"
|
||||
on_flagged_action: passthrough # or "block" or "monitor"
|
||||
violation_threshold: 0.5 # score >= threshold is flagged
|
||||
reasoning_mode: hybrid # off | hybrid | thinking
|
||||
categories:
|
||||
safety: "Detect jailbreaks and policy violations"
|
||||
policy_id: "your-cygnal-policy-id"
|
||||
policy_id: "your-cygnal-policy-id" # Optional: Your Cygnal policy ID. Defaults to a content safety policy if empty.
|
||||
streaming_end_of_stream_only: true # For streaming API, only send the assembled message to Cygnal (post_call only). Defaults to false.
|
||||
default_on: true
|
||||
guardrail_timeout: 30 # Defaults to 30 seconds. Change accordingly.
|
||||
fail_open: true # Defaults to true; set to false to propagate guardrail errors.
|
||||
|
||||
general_settings:
|
||||
master_key: "your-litellm-master-key"
|
||||
|
|
@ -65,13 +72,13 @@ litellm --config config.yaml --port 4000
|
|||
|
||||
## Choosing Guardrail Modes
|
||||
|
||||
Gray Swan can run during `pre_call`, `during_call`, and `post_call` stages. Combine modes based on your latency and coverage requirements.
|
||||
Gray Swan can run during `pre_call`, `during_call`, and `post_call` stages. Combine modes based on your latency and coverage requirements.
|
||||
|
||||
| Mode | When it Runs | Protects | Typical Use Case |
|
||||
|--------------|-------------------|-----------------------|------------------|
|
||||
| `pre_call` | Before LLM call | User input only | Block prompt injection before it reaches the model |
|
||||
| `during_call`| Parallel to call | User input only | Low-latency monitoring without blocking |
|
||||
| `post_call` | After response | Full conversation | Scan output for policy violations, leaked secrets, or IPI |
|
||||
| `post_call` | After response | Model Outputs | Scan output for policy violations, leaked secrets, or IPI |
|
||||
|
||||
|
||||
When using `during_call` with `on_flagged_action: block` or `on_flagged_action: passthrough`:
|
||||
|
|
@ -81,87 +88,110 @@ When using `during_call` with `on_flagged_action: block` or `on_flagged_action:
|
|||
- The guardrail exception prevents the response from reaching the user, but **does not cancel the running LLM task**
|
||||
- This means you pay full LLM costs while returning an error/passthrough message to the user
|
||||
|
||||
**Recommendation:** For cost-sensitive applications, use `pre_call` and `post_call` instead of `during_call` for blocking or passthrough modes. Reserve `during_call` for `monitor` mode where you want low-latency logging without impacting the user experience.
|
||||
**Recommendation:** Use `pre_call` and `post_call` instead of `during_call` for `passthrough` (or `block`) `on_flagged_action` (see our recommended configuration above). Reserve `during_call` for `monitor` mode ONLY when you want low-latency logging without impacting the user experience.
|
||||
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="monitor" label="Monitor Only">
|
||||
---
|
||||
|
||||
```yaml
|
||||
guardrails:
|
||||
- guardrail_name: "cygnal-monitor-only"
|
||||
litellm_params:
|
||||
guardrail: grayswan
|
||||
mode: "during_call"
|
||||
api_key: os.environ/GRAYSWAN_API_KEY
|
||||
optional_params:
|
||||
on_flagged_action: monitor
|
||||
violation_threshold: 0.6
|
||||
default_on: true
|
||||
## Work with Claude Code
|
||||
|
||||
Follow the official litellm [guide](https://docs.litellm.ai/docs/tutorials/claude_responses_api) on setting up Claude Code with litellm, with the guardrail part mentioned above added to your litellm configuration. Cygnal natively supports coding agent policies defense. Define your own policy or use the provided coding policies on the platform. The example config we show above is also the recommended setup for Claude Code (with the `policy_id` replaced with an appropriate one).
|
||||
|
||||
---
|
||||
|
||||
## Per-request overrides via `extra_body`
|
||||
|
||||
You can override parts of the Gray Swan guardrail configuration on a per-request basis by passing `litellm_metadata.guardrails[*].grayswan.extra_body`.
|
||||
|
||||
`extra_body` is merged into the Cygnal request body and takes precedence over specific fields from `config.yaml`, which are `policy_id`, `violation_threshold`, and `reasoning_mode`.
|
||||
|
||||
If you include a `metadata` field inside `extra_body`, it is forwarded to the Cygnal API as-is under the request body's `metadata` field.
|
||||
|
||||
Example:
|
||||
|
||||
```bash
|
||||
curl -X POST "http://0.0.0.0:4000/v1/messages?beta=true" \
|
||||
-H "Authorization: Bearer token" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "openrouter/anthropic/claude-sonnet-4.5",
|
||||
"messages": [{"role": "user", "content": "hello"}],
|
||||
"litellm_metadata": {
|
||||
"guardrails": [
|
||||
{
|
||||
"cygnal-monitor": {
|
||||
"extra_body": {
|
||||
"policy_id": "specific policy id you want to use",
|
||||
"metadata": {
|
||||
"user": "health-check"
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
Best for visibility without blocking. Alerts are logged via LiteLLM’s standard logging callbacks.
|
||||
OpenAI client:
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="block-input" label="Block Input">
|
||||
```python
|
||||
from openai import OpenAI
|
||||
|
||||
```yaml
|
||||
guardrails:
|
||||
- guardrail_name: "cygnal-block-input"
|
||||
litellm_params:
|
||||
guardrail: grayswan
|
||||
mode: "pre_call"
|
||||
api_key: os.environ/GRAYSWAN_API_KEY
|
||||
optional_params:
|
||||
on_flagged_action: block
|
||||
violation_threshold: 0.4
|
||||
categories:
|
||||
pii: "Detect sensitive data"
|
||||
default_on: true
|
||||
client = OpenAI(api_key="anything", base_url="http://0.0.0.0:4000")
|
||||
|
||||
resp = client.responses.create(
|
||||
model="openrouter/anthropic/claude-sonnet-4.5",
|
||||
input="hello",
|
||||
extra_body={
|
||||
"litellm_metadata": {
|
||||
"guardrails": [
|
||||
{
|
||||
"cygnal-monitor": {
|
||||
"extra_body": {
|
||||
"policy_id": "69038214e5cdb6befc5e991e",
|
||||
"metadata": {"trace_id": "trace-123"},
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
},
|
||||
)
|
||||
```
|
||||
|
||||
Stops malicious or sensitive prompts before any tokens are generated.
|
||||
Anthropic client:
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="full-coverage" label="Full Coverage">
|
||||
```python
|
||||
from anthropic import Anthropic
|
||||
|
||||
```yaml
|
||||
guardrails:
|
||||
- guardrail_name: "cygnal-full-coverage"
|
||||
litellm_params:
|
||||
guardrail: grayswan
|
||||
mode: [pre_call, post_call]
|
||||
api_key: os.environ/GRAYSWAN_API_KEY
|
||||
optional_params:
|
||||
on_flagged_action: block
|
||||
violation_threshold: 0.5
|
||||
reasoning_mode: thinking
|
||||
policy_id: "policy-id-from-grayswan"
|
||||
default_on: true
|
||||
client = Anthropic(api_key="anything", base_url="http://0.0.0.0:4000")
|
||||
|
||||
resp = client.messages.create(
|
||||
model="openrouter/anthropic/claude-sonnet-4.5",
|
||||
max_tokens=256,
|
||||
messages=[{"role": "user", "content": "hello"}],
|
||||
extra_body={
|
||||
"litellm_metadata": {
|
||||
"guardrails": [
|
||||
{
|
||||
"cygnal-monitor": {
|
||||
"extra_body": {
|
||||
"policy_id": "69038214e5cdb6befc5e991e",
|
||||
"metadata": {"trace_id": "trace-123"},
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
},
|
||||
)
|
||||
```
|
||||
|
||||
Provides the strongest enforcement by inspecting both prompts and responses.
|
||||
Notes:
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="passthrough" label="Passthrough Mode">
|
||||
|
||||
```yaml
|
||||
guardrails:
|
||||
- guardrail_name: "cygnal-passthrough"
|
||||
litellm_params:
|
||||
guardrail: grayswan
|
||||
mode: [pre_call, post_call]
|
||||
api_key: os.environ/GRAYSWAN_API_KEY
|
||||
optional_params:
|
||||
on_flagged_action: passthrough
|
||||
violation_threshold: 0.5
|
||||
default_on: true
|
||||
```
|
||||
|
||||
Allows requests to proceed without raising a 400 error when content is flagged. Instead of blocking, the model response content is replaced with a detailed violation message including violation score, violated rules, and detection flags (mutation, IPI). **Supported Response Formats:** OpenAI chat/text completions, Anthropic Messages API. Other response types (embeddings, images, etc.) will log a warning and return unchanged.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
- The guardrail name (for example, `cygnal-monitor`) must match the `guardrail_name` in `config.yaml`.
|
||||
- Per-request guardrail overrides may require a premium license, depending on your proxy settings.
|
||||
|
||||
---
|
||||
|
||||
|
|
@ -170,9 +200,14 @@ Allows requests to proceed without raising a 400 error when content is flagged.
|
|||
| Parameter | Type | Description |
|
||||
|---------------------------------------|-----------------|-------------|
|
||||
| `api_key` | string | Gray Swan Cygnal API key. Reads from `GRAYSWAN_API_KEY` if omitted. |
|
||||
| `api_base` | string | Override for the Gray Swan API base URL. Defaults to `https://api.grayswan.ai` or `GRAYSWAN_API_BASE`. |
|
||||
| `mode` | string or list | Guardrail stages (`pre_call`, `during_call`, `post_call`). |
|
||||
| `optional_params.on_flagged_action` | string | `monitor` (log only), `block` (raise `HTTPException`), or `passthrough` (replace response content with violation message, no 400 error). |
|
||||
| `.optional_params.violation_threshold`| number (0-1) | Scores at or above this value are considered violations. |
|
||||
| `optional_params.violation_threshold` | number (0-1) | Scores at or above this value are considered violations. |
|
||||
| `optional_params.reasoning_mode` | string | `off`, `hybrid`, or `thinking`. Enables Cygnal's reasoning capabilities. |
|
||||
| `optional_params.categories` | object | Map of custom category names to descriptions. |
|
||||
| `optional_params.policy_id` | string | Gray Swan policy identifier. |
|
||||
| `guardrail_timeout` | number | Timeout in seconds for the Cygnal request. Defaults to 30. |
|
||||
| `fail_open` | boolean | If true, errors contacting Cygnal are logged and the request proceeds; if false, errors propagate. Defaults to treu. |
|
||||
| `streaming_end_of_stream_only` | boolean | For streaming `post_call`, only send the final assembled response to Cygnal. Defaults to false. |
|
||||
| `default_on` | boolean | Run the guardrail on every request by default. |
|
||||
|
|
|
|||
|
|
@ -1,3 +1,7 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# [Beta] Guardrail Policies
|
||||
|
||||
Use policies to group guardrails and control which ones run for specific teams, keys, or models.
|
||||
|
|
@ -10,6 +14,9 @@ Use policies to group guardrails and control which ones run for specific teams,
|
|||
|
||||
## Quick Start
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="config" label="config.yaml">
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
|
|
@ -43,6 +50,26 @@ policy_attachments:
|
|||
scope: "*" # apply to all requests
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="ui" label="UI (LiteLLM Dashboard)">
|
||||
|
||||
**Step 1: Create a Policy**
|
||||
|
||||
Go to **Policies** tab and click **+ Create New Policy**. Fill in the policy name, description, and select guardrails to add.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
Response headers show what ran:
|
||||
|
||||
```
|
||||
|
|
@ -58,6 +85,9 @@ x-litellm-applied-guardrails: pii_masking,prompt_injection
|
|||
|
||||
You have a global baseline, but want to add extra guardrails for a specific team.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="config" label="config.yaml">
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
policies:
|
||||
global-baseline:
|
||||
|
|
@ -81,6 +111,30 @@ policy_attachments:
|
|||
- finance # team alias from /team/new
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="ui" label="UI (LiteLLM Dashboard)">
|
||||
|
||||
**Option 1: Create a team-scoped attachment**
|
||||
|
||||
Go to **Policies** > **Attachments** tab and click **+ Create New Attachment**. Select the policy and the teams to scope it to.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
**Option 2: Attach from team settings**
|
||||
|
||||
Go to **Teams** > click on a team > **Settings** tab > under **Policies**, select the policies to attach.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
<Image img={require('../../../img/policy_team_attach.png')} />
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
Now the `finance` team gets `pii_masking` + `strict_compliance_check` + `audit_logger`, while everyone else just gets `pii_masking`.
|
||||
|
||||
## Remove guardrails for a specific team
|
||||
|
|
@ -201,6 +255,60 @@ policy_attachments:
|
|||
- "test-*" # key alias pattern
|
||||
```
|
||||
|
||||
**Tag-based** (matches keys/teams by metadata tags, wildcards supported):
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
policy_attachments:
|
||||
- policy: hipaa-compliance
|
||||
tags:
|
||||
- "healthcare"
|
||||
- "health-*" # wildcard - matches health-team, health-dev, etc.
|
||||
```
|
||||
|
||||
Tags are read from key and team `metadata.tags`. For example, a key created with `metadata: {"tags": ["healthcare"]}` would match the attachment above.
|
||||
|
||||
## Test Policy Matching
|
||||
|
||||
Debug which policies and guardrails apply for a given context. Use this to verify your policy configuration before deploying.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI (LiteLLM Dashboard)">
|
||||
|
||||
Go to **Policies** > **Test** tab. Enter a team alias, key alias, model, or tags and click **Test** to see which policies match and what guardrails would be applied.
|
||||
|
||||
<Image img={require('../../../img/policy_test_matching.png')} />
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
```bash
|
||||
curl -X POST "http://localhost:4000/policies/resolve" \
|
||||
-H "Authorization: Bearer <your_api_key>" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"tags": ["healthcare"],
|
||||
"model": "gpt-4"
|
||||
}'
|
||||
```
|
||||
|
||||
Response:
|
||||
|
||||
```json
|
||||
{
|
||||
"effective_guardrails": ["pii_masking"],
|
||||
"matched_policies": [
|
||||
{
|
||||
"policy_name": "hipaa-compliance",
|
||||
"matched_via": "tag:healthcare",
|
||||
"guardrails_added": ["pii_masking"]
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Config Reference
|
||||
|
||||
### `policies`
|
||||
|
|
@ -233,14 +341,18 @@ policy_attachments:
|
|||
scope: ...
|
||||
teams: [...]
|
||||
keys: [...]
|
||||
models: [...]
|
||||
tags: [...]
|
||||
```
|
||||
|
||||
| Field | Type | Description |
|
||||
|-------|------|-------------|
|
||||
| `policy` | `string` | **Required.** Name of the policy to attach. |
|
||||
| `scope` | `string` | Use `"*"` to apply globally. |
|
||||
| `teams` | `list[string]` | Team aliases (from `/team/new`). |
|
||||
| `teams` | `list[string]` | Team aliases (from `/team/new`). Supports `*` wildcard. |
|
||||
| `keys` | `list[string]` | Key aliases (from `/key/generate`). Supports `*` wildcard. |
|
||||
| `models` | `list[string]` | Model names. Supports `*` wildcard. |
|
||||
| `tags` | `list[string]` | Tag patterns (from key/team `metadata.tags`). Supports `*` wildcard. |
|
||||
|
||||
### Response Headers
|
||||
|
||||
|
|
@ -248,6 +360,7 @@ policy_attachments:
|
|||
|--------|-------------|
|
||||
| `x-litellm-applied-policies` | Policies that matched this request |
|
||||
| `x-litellm-applied-guardrails` | Guardrails that actually ran |
|
||||
| `x-litellm-policy-sources` | Why each policy matched (e.g., `hipaa=tag:healthcare; baseline=scope:*`) |
|
||||
|
||||
## How it works
|
||||
|
||||
|
|
|
|||
139
docs/my-website/docs/proxy/guardrails/policy_tags.md
Normal file
|
|
@ -0,0 +1,139 @@
|
|||
# Tag-Based Policy Attachments
|
||||
|
||||
Apply guardrail policies automatically to any key or team that has a specific tag. Instead of attaching policies one-by-one, tag your keys and let the policy engine handle the rest.
|
||||
|
||||
**Example:** Your security team requires all healthcare-related keys to run PII masking and PHI detection. Tag those keys with `health`, create a single tag-based attachment, and every matching key gets the guardrails automatically.
|
||||
|
||||
## 1. Create a Policy with Guardrails
|
||||
|
||||
Navigate to **Policies** in the left sidebar. You'll see a list of existing policies along with their guardrails.
|
||||
|
||||
|
||||
|
||||
Click **+ Add New Policy**. In the modal, enter a name for your policy (e.g., `high-risk-policy2`). You can also type to search existing policy names if you want to reference them.
|
||||
|
||||
|
||||
|
||||
Scroll down to **Guardrails to Add**. Click the dropdown to see all available guardrails configured on your proxy — select the ones this policy should enforce.
|
||||
|
||||
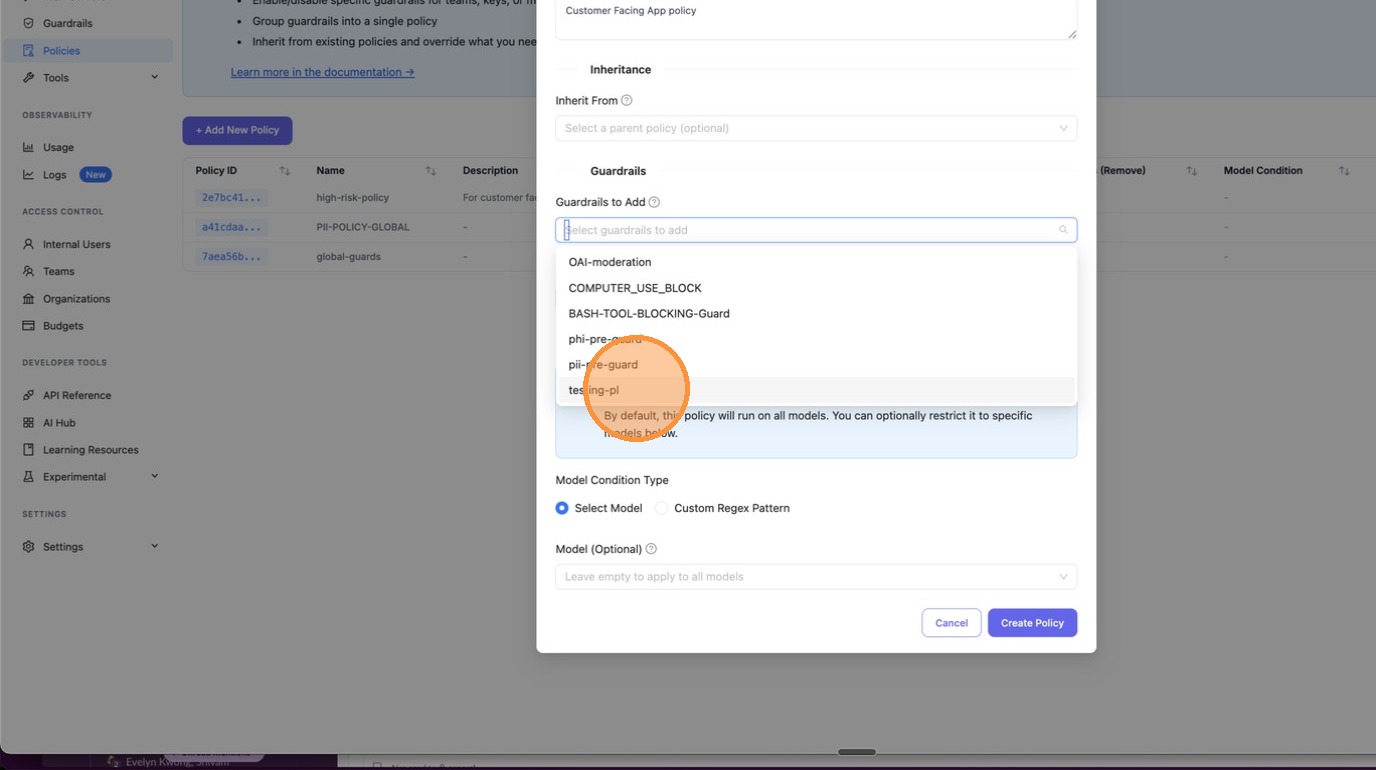
|
||||
|
||||
After selecting your guardrails, they appear as chips in the input field. The **Resolved Guardrails** section below shows the final set that will be applied (including any inherited from a parent policy).
|
||||
|
||||
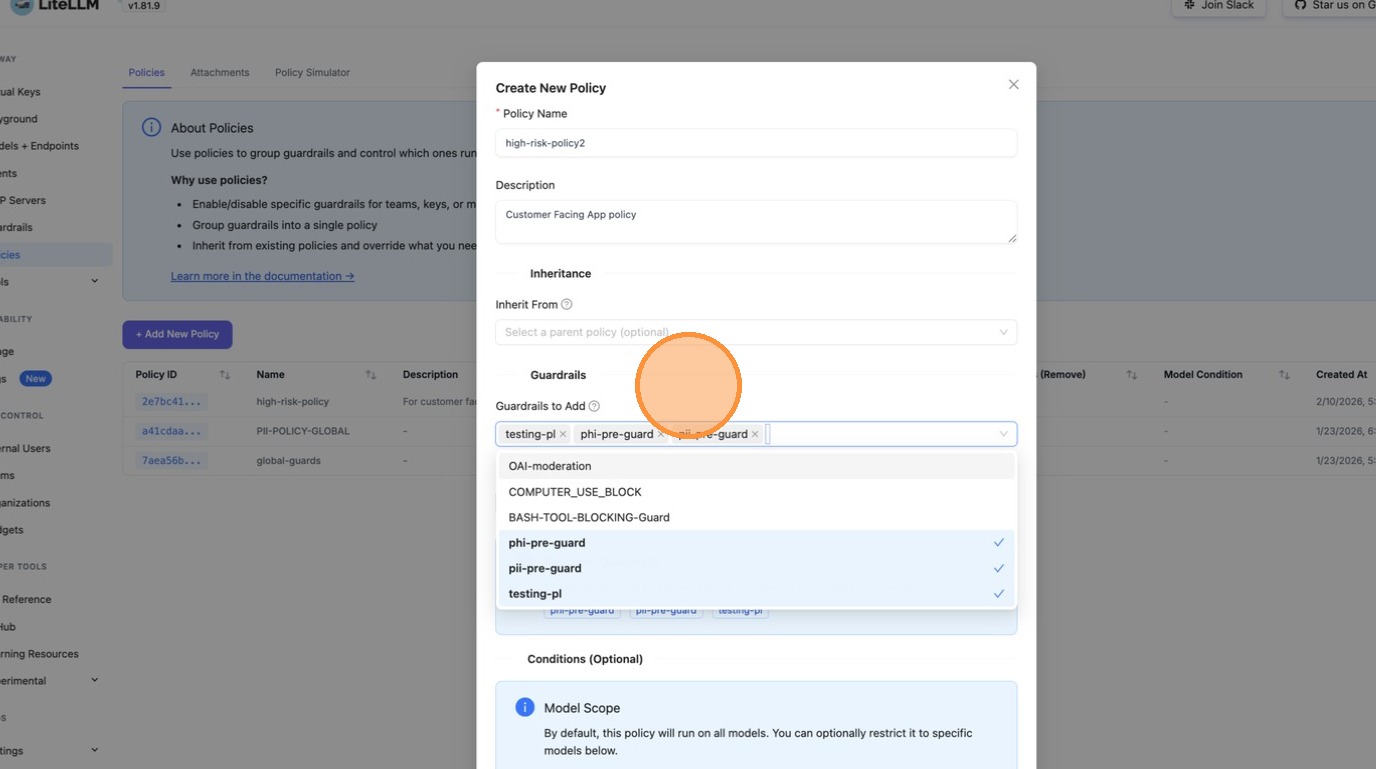
|
||||
|
||||
Click **Create Policy** to save.
|
||||
|
||||
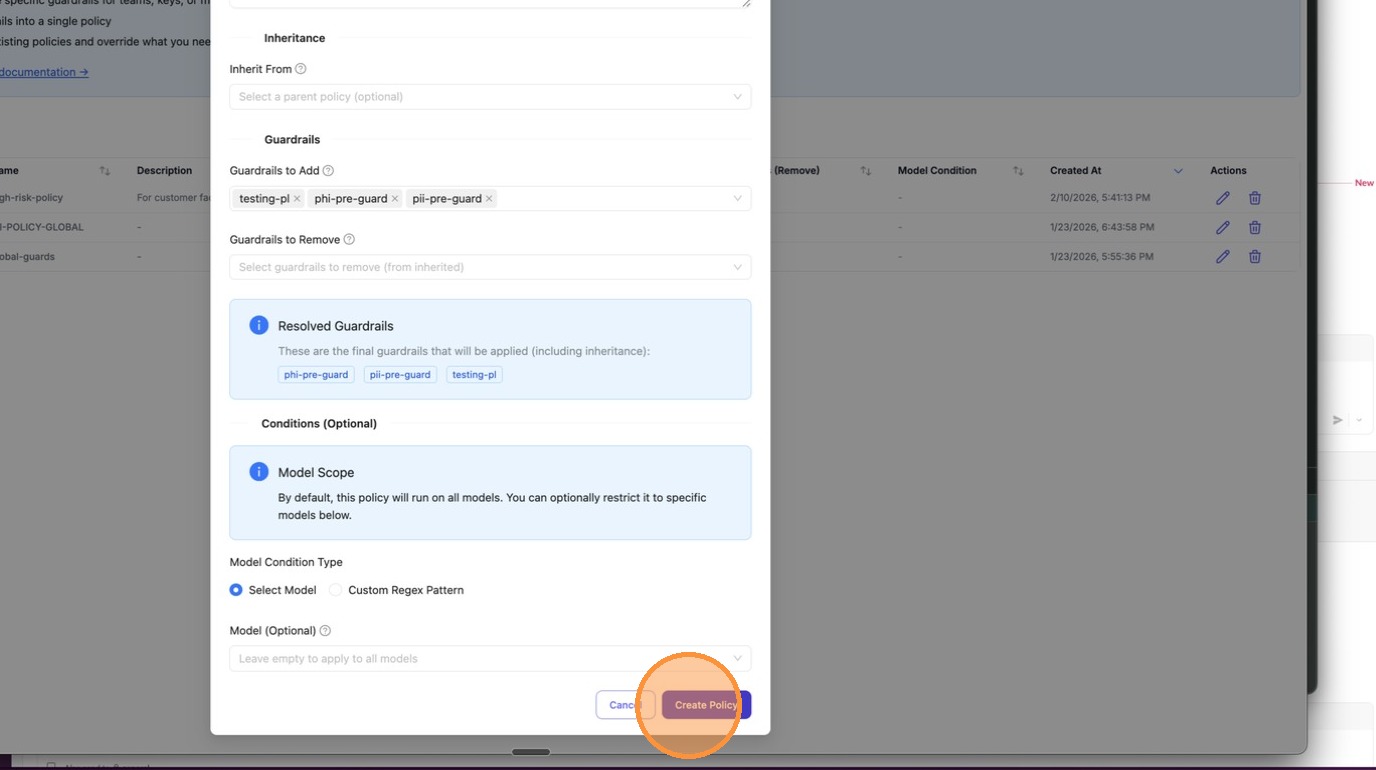
|
||||
|
||||
## 2. Add a Tag Attachment for the Policy
|
||||
|
||||
After creating the policy, switch to the **Attachments** tab. This is where you define *where* the policy applies.
|
||||
|
||||
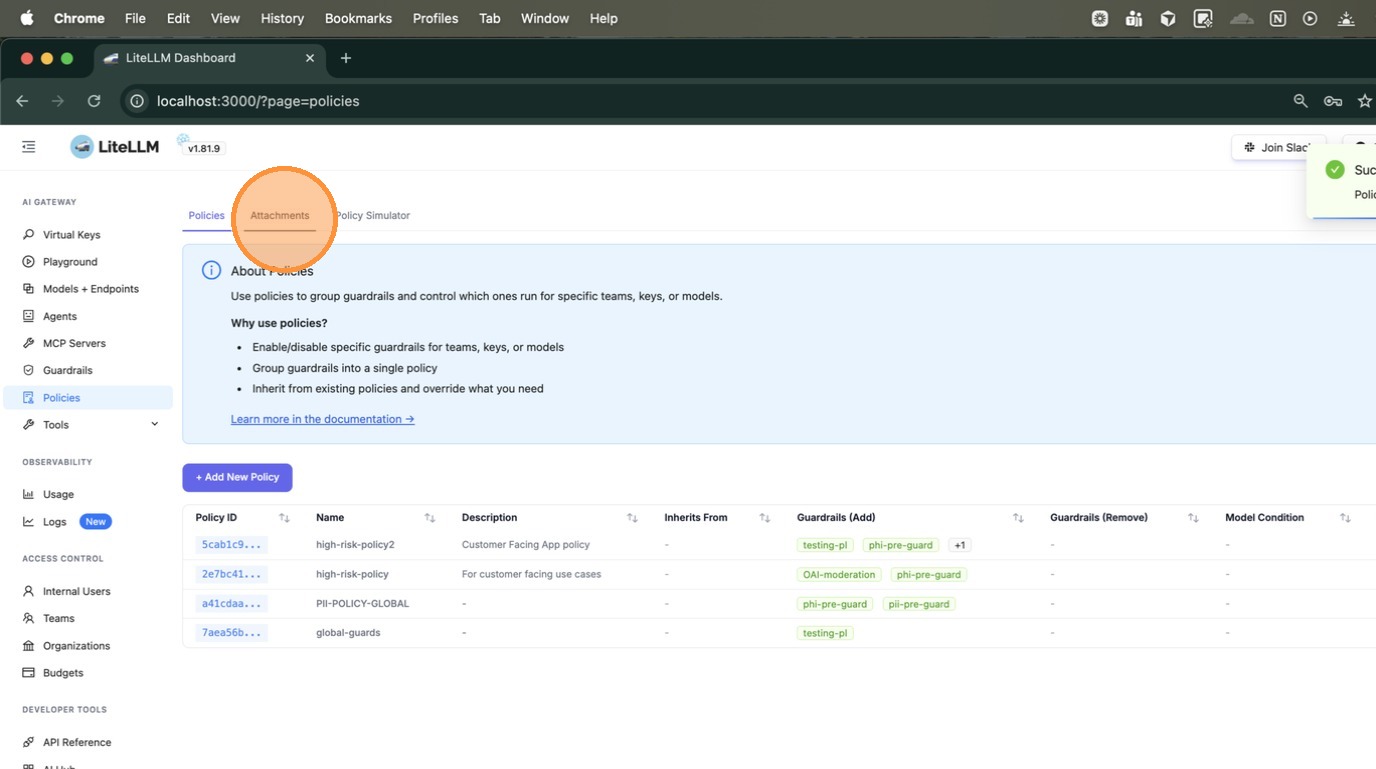
|
||||
|
||||
Click **+ Add New Attachment**. The Attachments page explains the available scopes: Global, Teams, Keys, Models, and **Tags**.
|
||||
|
||||
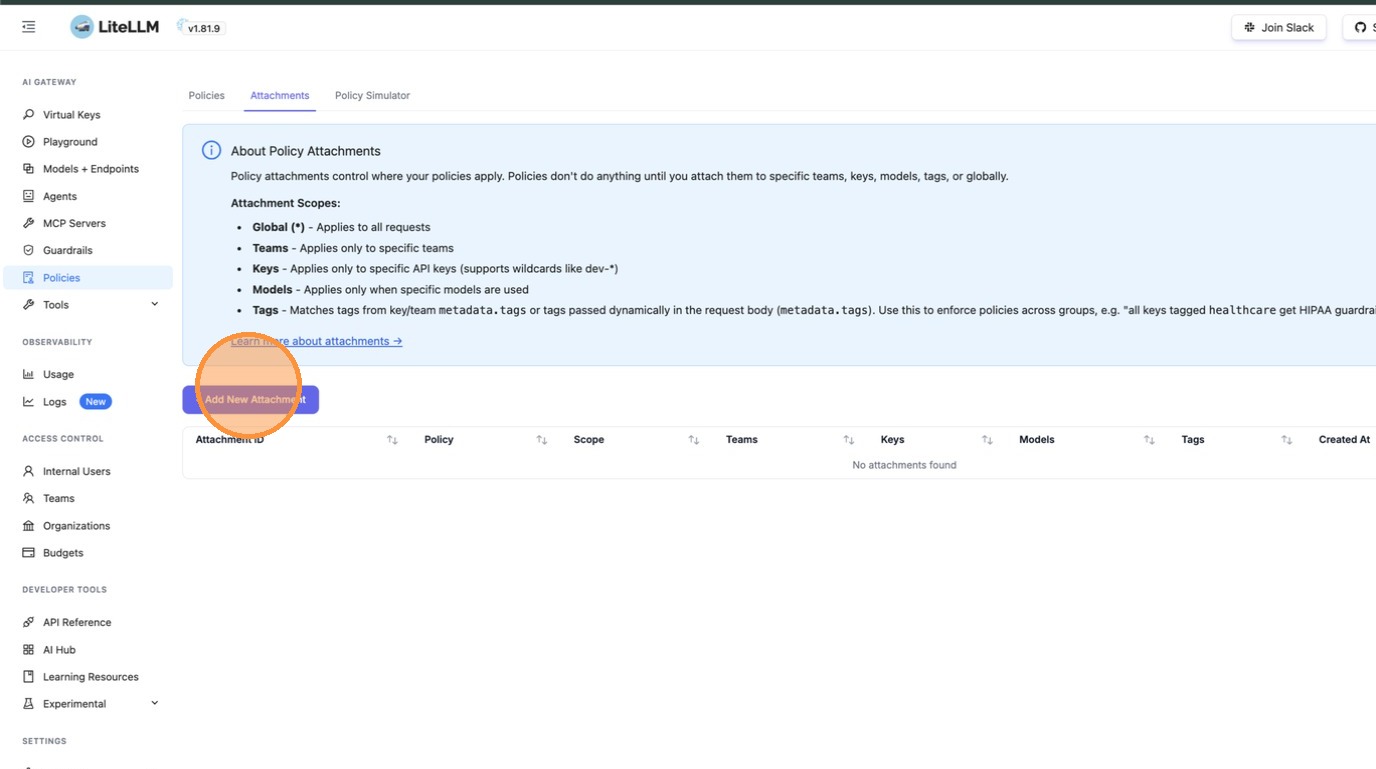
|
||||
|
||||
In the **Create Policy Attachment** modal, first select the policy you just created from the dropdown.
|
||||
|
||||
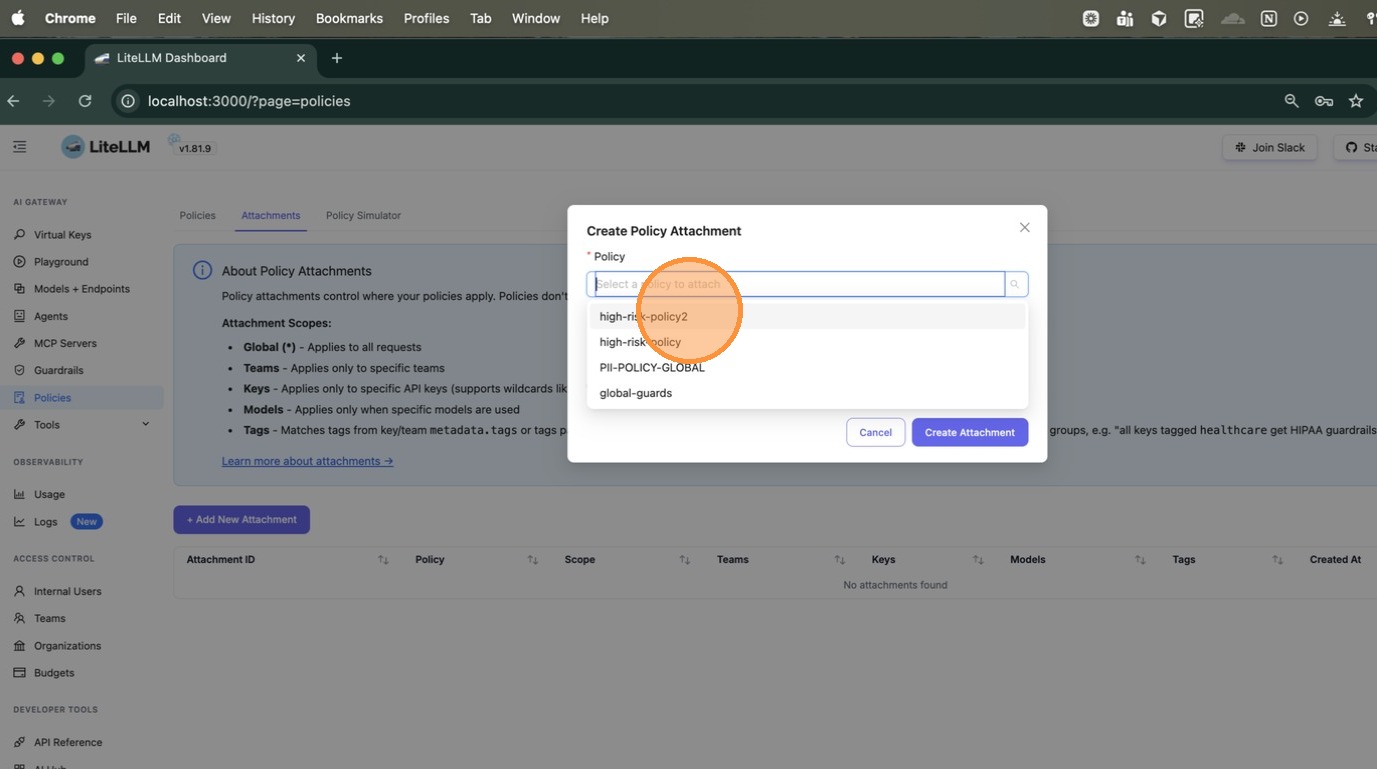
|
||||
|
||||
Choose **Specific (teams, keys, models, or tags)** as the scope type. This expands the form to show fields for Teams, Keys, Models, and Tags.
|
||||
|
||||
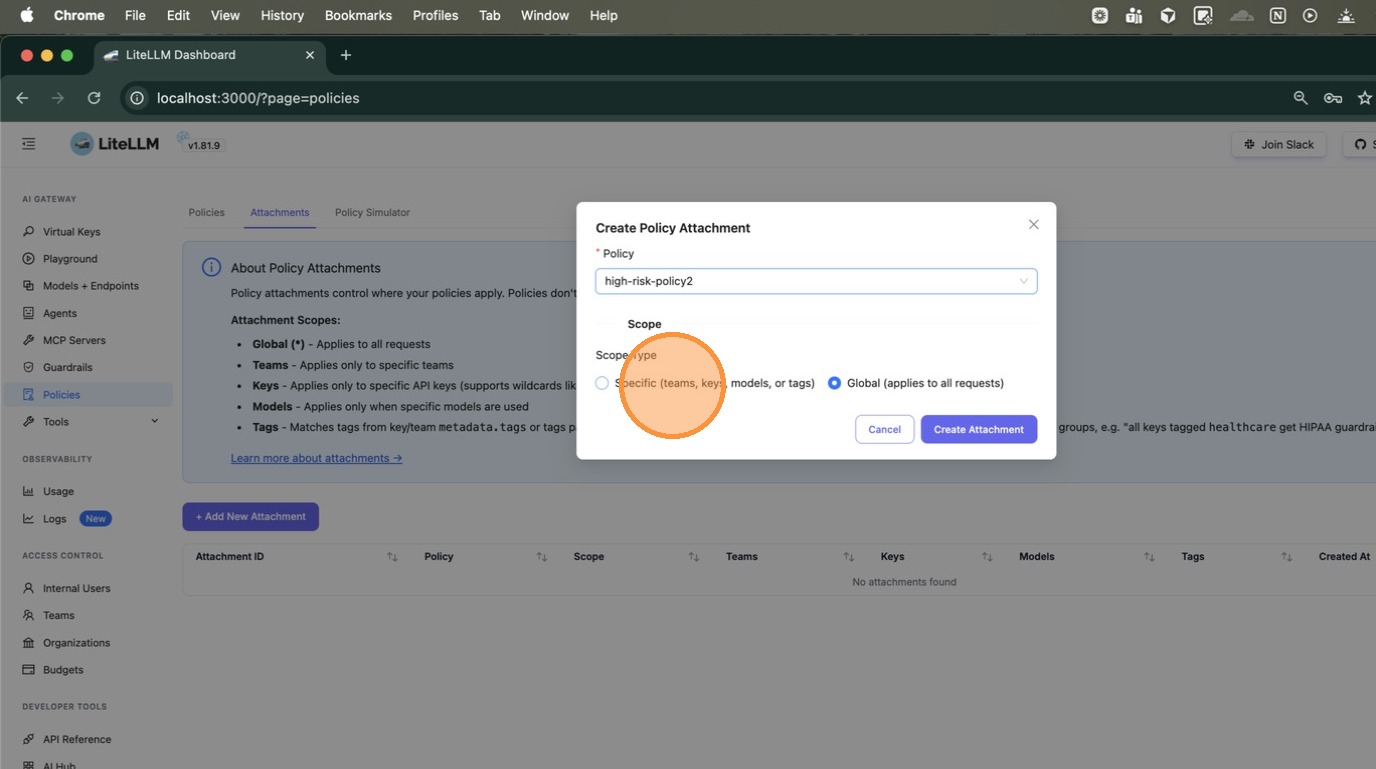
|
||||
|
||||
Scroll down to the **Tags** field and type the tag to match — here we enter `health`. You can enter any string, or use a wildcard pattern like `health-*` to match all tags starting with `health-` (e.g., `health-team`, `health-dev`).
|
||||
|
||||
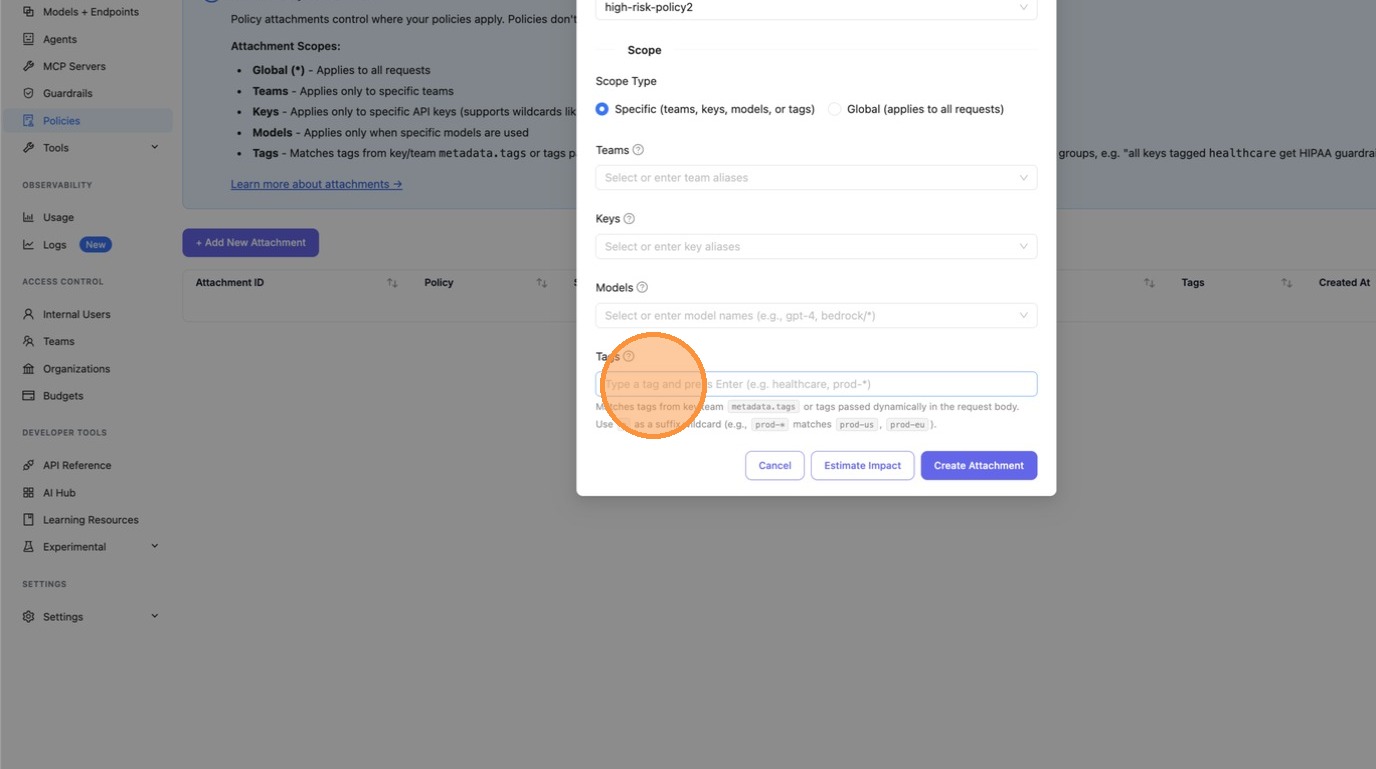
|
||||
|
||||
## 3. Check the Impact of the Attachment
|
||||
|
||||
Before creating the attachment, click **Estimate Impact** to preview how many keys and teams would be affected. This is your blast-radius check — make sure the scope is what you expect before applying.
|
||||
|
||||
|
||||
|
||||
The **Impact Preview** appears inline, showing exactly how many keys and teams would be affected. In this example: "This attachment would affect **1 key** and **0 teams**", with the key alias `hi` listed.
|
||||
|
||||
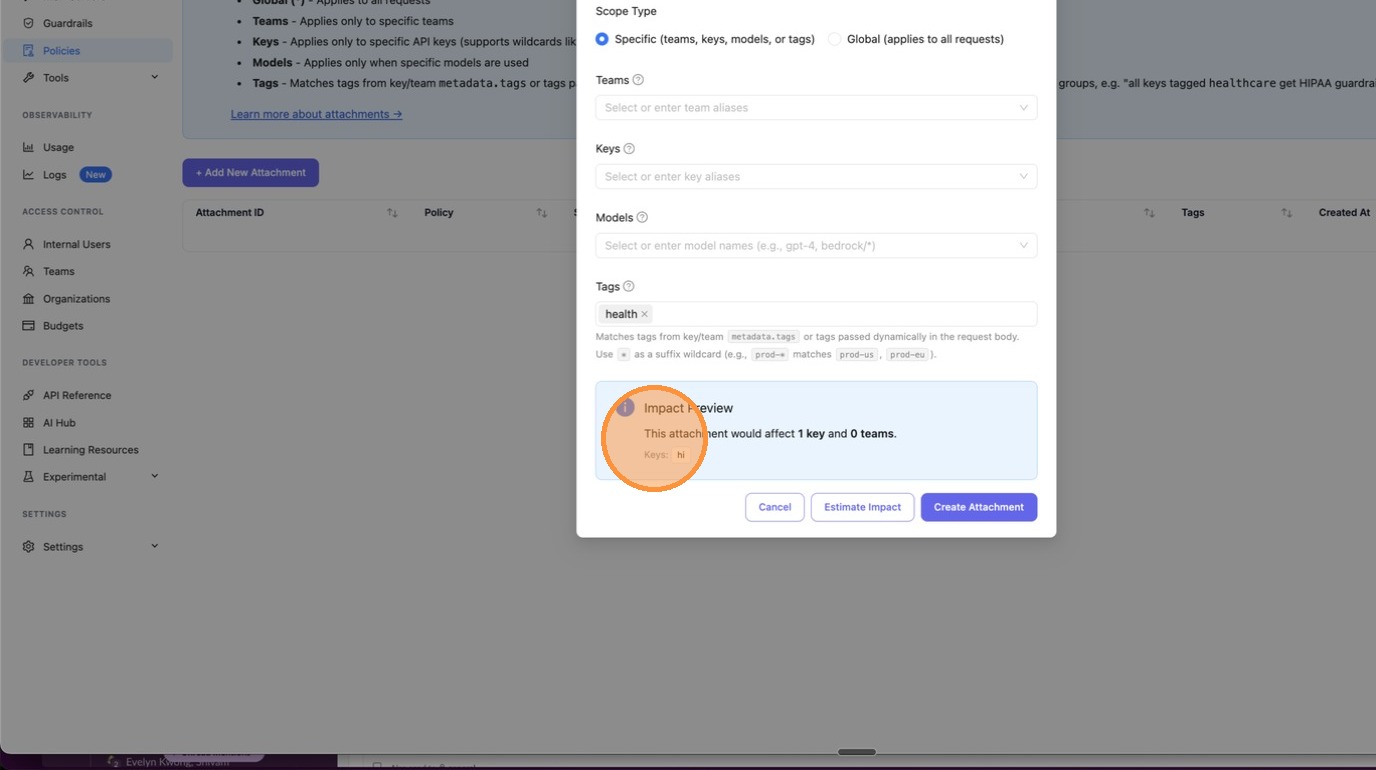
|
||||
|
||||
Once you're satisfied with the impact, click **Create Attachment** to save.
|
||||
|
||||
|
||||
|
||||
The attachment now appears in the table with the policy name `high-risk-policy2` and tag `health` visible.
|
||||
|
||||
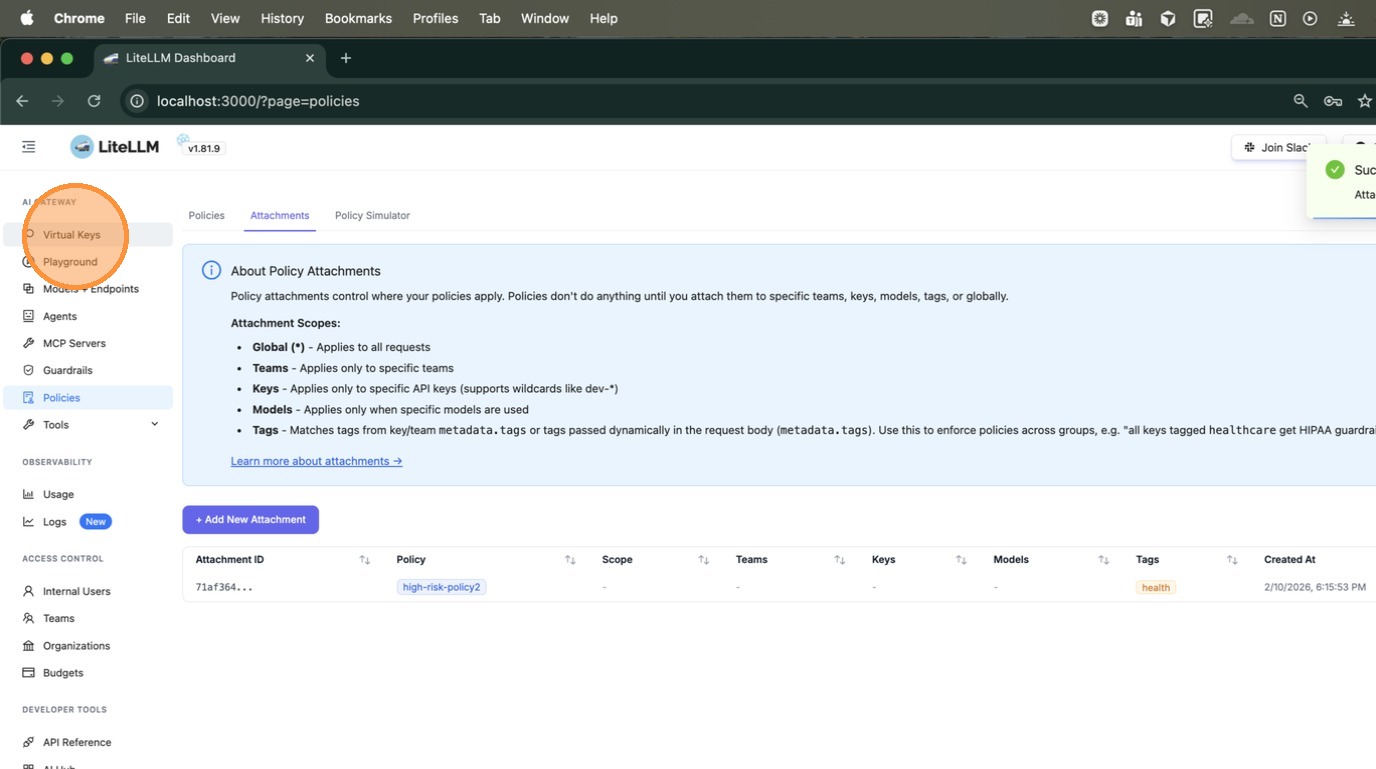
|
||||
|
||||
## 4. Create a Key with the Tag
|
||||
|
||||
Navigate to **Virtual Keys** in the left sidebar. Click **+ Create New Key**.
|
||||
|
||||
|
||||
|
||||
Enter a key name and select a model. Then expand **Optional Settings** and scroll down to the **Tags** field.
|
||||
|
||||
|
||||
|
||||
In the **Tags** field, type `health` and press Enter. This is the tag the policy engine will match against.
|
||||
|
||||
|
||||
|
||||
The tag `health` now appears as a chip in the Tags field. Confirm your settings look correct.
|
||||
|
||||
|
||||
|
||||
Click **Create Key** at the bottom of the form.
|
||||
|
||||
|
||||
|
||||
A dialog appears with your new virtual key. Click **Copy Virtual Key** — you'll need this to test in the next step.
|
||||
|
||||
|
||||
|
||||
## 5. Test the Key and Validate the Policy is Applied
|
||||
|
||||
Navigate to **Playground** in the left sidebar to test the key interactively.
|
||||
|
||||
|
||||
|
||||
Under **Virtual Key Source**, select "Virtual Key" and paste the key you just copied into the input field.
|
||||
|
||||
|
||||
|
||||
Select a model from the **Select Model** dropdown.
|
||||
|
||||
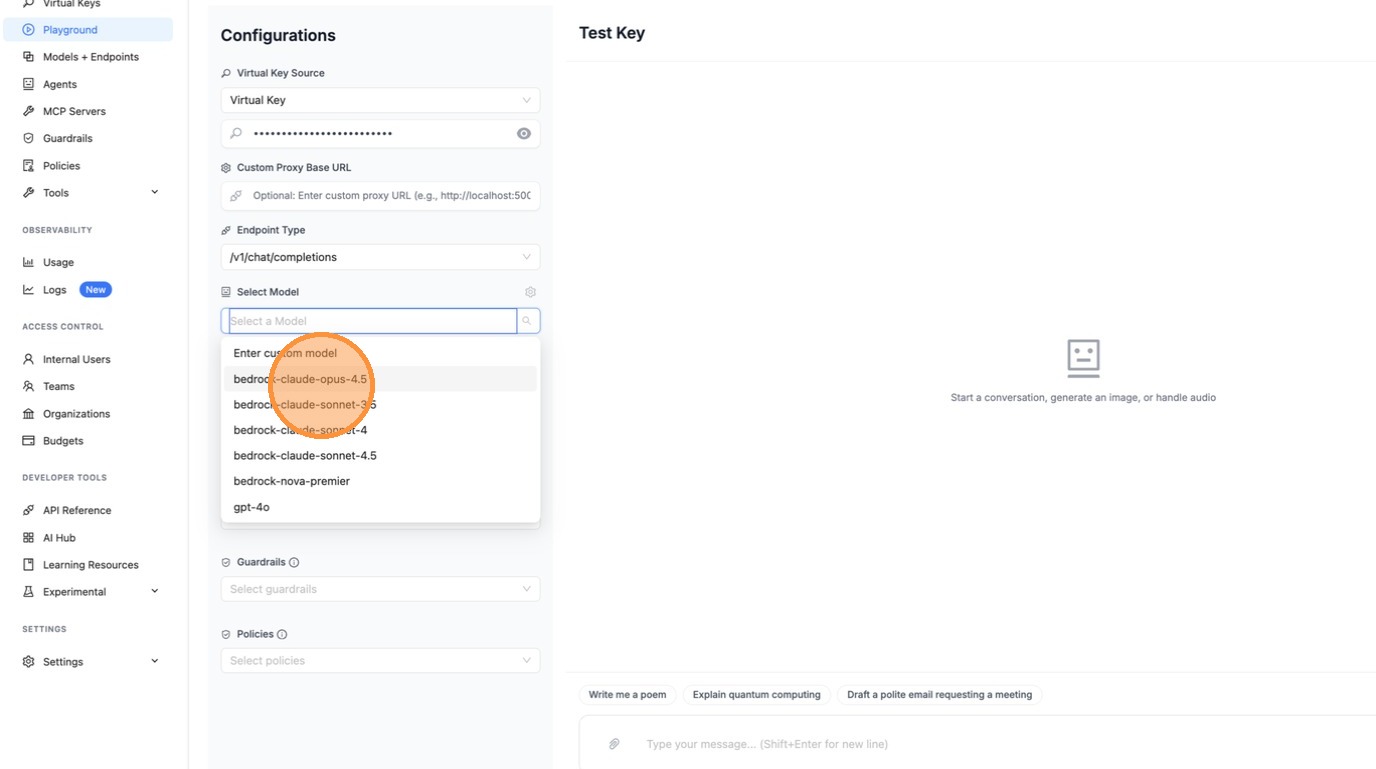
|
||||
|
||||
Type a message and press Enter. If a guardrail blocks the request, you'll see it in the response. In this example, the `testing-pl` guardrail detected an email pattern and returned a 403 error — confirming the policy is working.
|
||||
|
||||
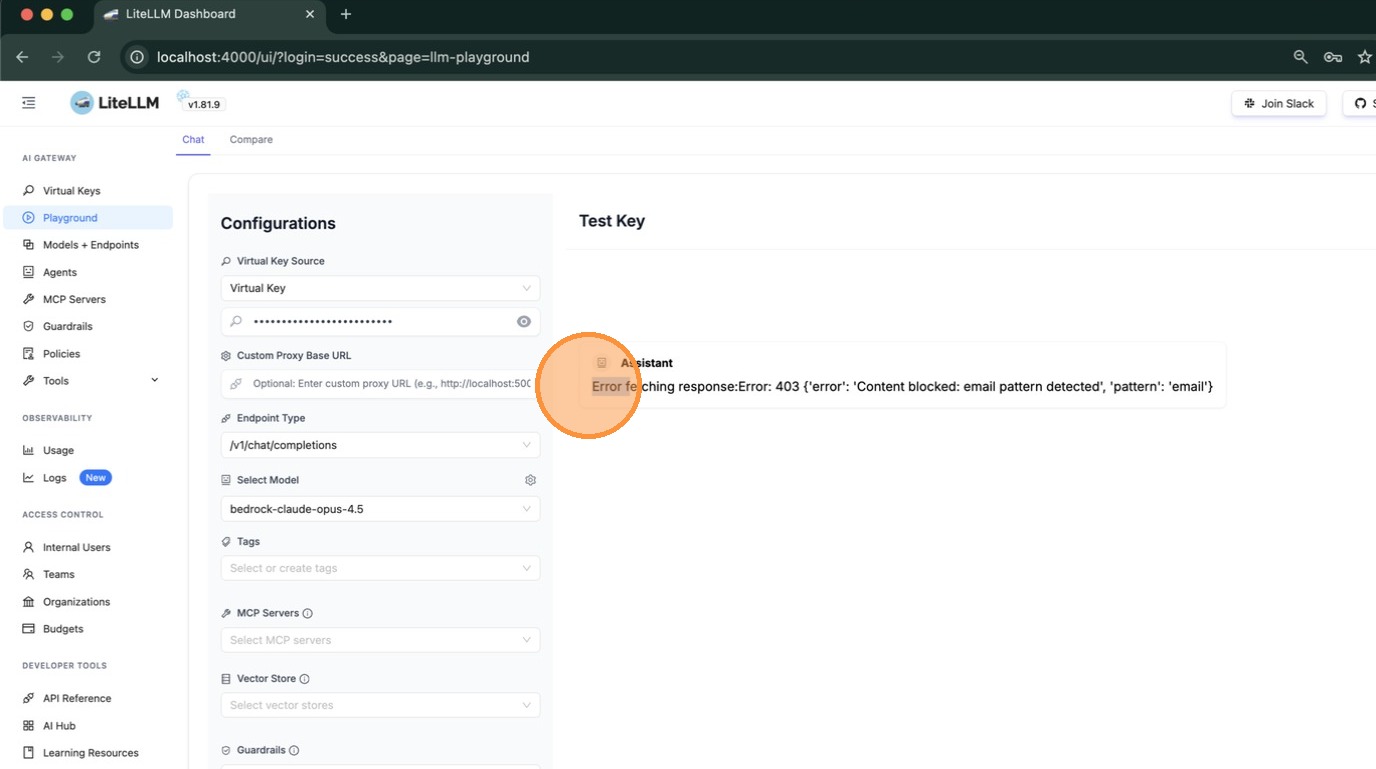
|
||||
|
||||
**Using curl:**
|
||||
|
||||
You can also verify via the command line. The response headers confirm which policies and guardrails were applied:
|
||||
|
||||
```bash
|
||||
curl -v http://localhost:4000/chat/completions \
|
||||
-H "Authorization: Bearer <your-tagged-key>" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "gpt-4o",
|
||||
"messages": [{"role": "user", "content": "say hi"}]
|
||||
}'
|
||||
```
|
||||
|
||||
Check the response headers:
|
||||
|
||||
```
|
||||
x-litellm-applied-policies: high-risk-policy2
|
||||
x-litellm-applied-guardrails: pii-pre-guard,phi-pre-guard,testing-pl
|
||||
x-litellm-policy-sources: high-risk-policy2=tag:health
|
||||
```
|
||||
|
||||
| Header | What it tells you |
|
||||
|--------|-------------------|
|
||||
| `x-litellm-applied-policies` | Which policies matched this request |
|
||||
| `x-litellm-applied-guardrails` | Which guardrails actually ran |
|
||||
| `x-litellm-policy-sources` | **Why** each policy matched — `tag:health` confirms it was the tag |
|
||||
296
docs/my-website/docs/proxy/guardrails/policy_templates.md
Normal file
|
|
@ -0,0 +1,296 @@
|
|||
# Policy Templates
|
||||
|
||||
Policy templates provide pre-configured guardrail policies that you can use as a starting point for your organization. Instead of manually creating policies and guardrails, you can select a template that matches your use case and deploy it with one click.
|
||||
|
||||
## Using Policy Templates
|
||||
|
||||
### In the UI
|
||||
|
||||
1. Navigate to **Policies → Templates** tab in the LiteLLM Admin UI
|
||||
2. Browse available templates (e.g., "PII Protection", "Cost Control", "HR Compliance")
|
||||
3. Click **"Use Template"** on any template
|
||||
4. Review the guardrails that will be created:
|
||||
- Existing guardrails are marked with a green checkmark
|
||||
- New guardrails can be selected/deselected
|
||||
5. Click **"Create X Guardrails & Use Template"**
|
||||
6. Review and customize the pre-filled policy form
|
||||
7. Click **"Create Policy"** to save
|
||||
|
||||
### Workflow
|
||||
|
||||
```
|
||||
Select Template → Review Guardrails → Create Selected → Edit Policy → Save
|
||||
```
|
||||
|
||||
The system automatically:
|
||||
- ✅ Detects which guardrails already exist
|
||||
- ✅ Creates only the missing guardrails you select
|
||||
- ✅ Pre-fills the policy form with template data
|
||||
- ✅ Lets you customize before saving
|
||||
|
||||
## Available Templates
|
||||
|
||||
Templates are fetched from [GitHub](https://raw.githubusercontent.com/BerriAI/litellm/main/policy_templates.json) with automatic fallback to local backup.
|
||||
|
||||
### Current Templates
|
||||
|
||||
#### 1. Advanced PII Protection (Australia)
|
||||
- **Complexity:** High
|
||||
- **Use Case:** Comprehensive PII detection for Australian organizations
|
||||
- **Guardrails:**
|
||||
- Australian tax identifiers (TFN, ABN, Medicare)
|
||||
- Australian passports
|
||||
- International PII (SSN, passports, national IDs)
|
||||
- Contact information (email, phone, address)
|
||||
- Financial data (credit cards, IBAN)
|
||||
- API credentials (AWS, GitHub, Slack) - **BLOCKS** requests
|
||||
- Network infrastructure (IP addresses)
|
||||
- Protected class information (gender, race, religion, disability, etc.)
|
||||
|
||||
#### 2. Baseline PII Protection
|
||||
- **Complexity:** Low
|
||||
- **Use Case:** Basic protection for internal tools and testing
|
||||
- **Guardrails:**
|
||||
- Australian tax identifiers
|
||||
- API credentials
|
||||
- Financial data
|
||||
|
||||
## Creating Your Own Policy Templates
|
||||
|
||||
You can contribute policy templates for the entire LiteLLM community to use.
|
||||
|
||||
### Template Structure
|
||||
|
||||
Templates are defined in JSON format with the following structure:
|
||||
|
||||
```json
|
||||
{
|
||||
"id": "unique-template-id",
|
||||
"title": "Display Title",
|
||||
"description": "Detailed description of what this template protects",
|
||||
"icon": "ShieldCheckIcon",
|
||||
"iconColor": "text-purple-500",
|
||||
"iconBg": "bg-purple-50",
|
||||
"guardrails": [
|
||||
"guardrail-name-1",
|
||||
"guardrail-name-2"
|
||||
],
|
||||
"complexity": "Low|Medium|High",
|
||||
"guardrailDefinitions": [
|
||||
{
|
||||
"guardrail_name": "example-guardrail",
|
||||
"litellm_params": {
|
||||
"guardrail": "litellm_content_filter",
|
||||
"mode": "pre_call",
|
||||
"patterns": [
|
||||
{
|
||||
"pattern_type": "prebuilt",
|
||||
"pattern_name": "email",
|
||||
"action": "MASK"
|
||||
}
|
||||
],
|
||||
"pattern_redaction_format": "[{pattern_name}_REDACTED]"
|
||||
},
|
||||
"guardrail_info": {
|
||||
"description": "What this guardrail does"
|
||||
}
|
||||
}
|
||||
],
|
||||
"templateData": {
|
||||
"policy_name": "policy-name",
|
||||
"description": "Policy description",
|
||||
"guardrails_add": ["guardrail-name-1", "guardrail-name-2"],
|
||||
"guardrails_remove": []
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Field Descriptions
|
||||
|
||||
#### Display Fields
|
||||
- **id**: Unique identifier (lowercase with hyphens)
|
||||
- **title**: User-facing name shown in UI
|
||||
- **description**: Detailed explanation of what the template protects
|
||||
- **icon**: Icon name (must be available in UI icon map)
|
||||
- **iconColor**: Tailwind CSS text color class
|
||||
- **iconBg**: Tailwind CSS background color class
|
||||
- **guardrails**: Array of guardrail names (for display only)
|
||||
- **complexity**: Badge showing difficulty ("Low", "Medium", or "High")
|
||||
|
||||
#### Guardrail Definitions
|
||||
- **guardrailDefinitions**: Array of complete guardrail configurations
|
||||
- Each must be a valid guardrail object that can be sent to `/guardrails` POST endpoint
|
||||
- If a guardrail already exists, it will be skipped
|
||||
- Can be empty `[]` if template uses only existing guardrails
|
||||
|
||||
#### Policy Configuration
|
||||
- **templateData**: Object that pre-fills the policy form
|
||||
- **policy_name**: Suggested name (user can edit)
|
||||
- **description**: Policy description
|
||||
- **guardrails_add**: Array of guardrail names to include
|
||||
- **guardrails_remove**: Array to remove (usually `[]` for templates)
|
||||
- **inherit**: (Optional) Parent policy name for inheritance
|
||||
|
||||
### Example Template
|
||||
|
||||
Here's a complete example for a HIPAA compliance template:
|
||||
|
||||
```json
|
||||
{
|
||||
"id": "hipaa-compliance",
|
||||
"title": "HIPAA Compliance Policy",
|
||||
"description": "Healthcare compliance policy that masks PHI and enforces HIPAA regulations for healthcare applications.",
|
||||
"icon": "ShieldCheckIcon",
|
||||
"iconColor": "text-red-500",
|
||||
"iconBg": "bg-red-50",
|
||||
"guardrails": [
|
||||
"phi-detector",
|
||||
"medical-record-blocker",
|
||||
"patient-id-masker"
|
||||
],
|
||||
"complexity": "High",
|
||||
"guardrailDefinitions": [
|
||||
{
|
||||
"guardrail_name": "phi-detector",
|
||||
"litellm_params": {
|
||||
"guardrail": "litellm_content_filter",
|
||||
"mode": "pre_call",
|
||||
"patterns": [
|
||||
{
|
||||
"pattern_type": "prebuilt",
|
||||
"pattern_name": "us_ssn",
|
||||
"action": "MASK"
|
||||
},
|
||||
{
|
||||
"pattern_type": "prebuilt",
|
||||
"pattern_name": "email",
|
||||
"action": "MASK"
|
||||
},
|
||||
{
|
||||
"pattern_type": "prebuilt",
|
||||
"pattern_name": "us_phone",
|
||||
"action": "MASK"
|
||||
}
|
||||
],
|
||||
"pattern_redaction_format": "[PHI_REDACTED]"
|
||||
},
|
||||
"guardrail_info": {
|
||||
"description": "Detects and masks Protected Health Information (PHI)"
|
||||
}
|
||||
}
|
||||
],
|
||||
"templateData": {
|
||||
"policy_name": "hipaa-compliance-policy",
|
||||
"description": "HIPAA compliance policy for healthcare applications",
|
||||
"guardrails_add": [
|
||||
"phi-detector",
|
||||
"medical-record-blocker",
|
||||
"patient-id-masker"
|
||||
],
|
||||
"guardrails_remove": []
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Contributing Templates
|
||||
|
||||
To contribute a policy template for everyone to use:
|
||||
|
||||
### Step 1: Create Your Template JSON
|
||||
|
||||
1. Create a JSON file following the structure above
|
||||
2. Test it locally by adding it to your local `policy_templates.json`
|
||||
3. Verify all guardrails work correctly
|
||||
4. Ensure descriptions are clear and helpful
|
||||
|
||||
### Step 2: Submit a Pull Request
|
||||
|
||||
1. Fork the [LiteLLM repository](https://github.com/BerriAI/litellm)
|
||||
2. Add your template to `policy_templates.json` at the root
|
||||
3. Add your template to `litellm/policy_templates_backup.json` (keep both in sync)
|
||||
4. Create a pull request with:
|
||||
- Clear description of what the template protects
|
||||
- Use case examples
|
||||
- Any relevant compliance frameworks (HIPAA, GDPR, SOC 2, etc.)
|
||||
|
||||
### Guidelines
|
||||
|
||||
**DO:**
|
||||
- ✅ Use clear, descriptive names
|
||||
- ✅ Include comprehensive descriptions
|
||||
- ✅ Test all guardrails thoroughly
|
||||
- ✅ Document pattern sources (e.g., "Based on NIST guidelines")
|
||||
- ✅ Group related guardrails logically
|
||||
- ✅ Consider different complexity levels
|
||||
|
||||
**DON'T:**
|
||||
- ❌ Include credentials or secrets
|
||||
- ❌ Use overly broad patterns that may have false positives
|
||||
- ❌ Duplicate existing templates
|
||||
- ❌ Use custom code without thorough testing
|
||||
|
||||
## Using Templates Offline
|
||||
|
||||
For air-gapped or offline deployments, set the environment variable:
|
||||
|
||||
```bash
|
||||
export LITELLM_LOCAL_POLICY_TEMPLATES=true
|
||||
```
|
||||
|
||||
This forces the system to use the local backup (`litellm/policy_templates_backup.json`) instead of fetching from GitHub.
|
||||
|
||||
## Template Sources
|
||||
|
||||
- **GitHub (default):** https://raw.githubusercontent.com/BerriAI/litellm/main/policy_templates.json
|
||||
- **Local backup:** `litellm/policy_templates_backup.json`
|
||||
|
||||
Templates are automatically fetched from GitHub on each request, with fallback to local backup on any failure.
|
||||
|
||||
## Available Pattern Types
|
||||
|
||||
When creating guardrails for templates, you can use these prebuilt patterns:
|
||||
|
||||
### Identity Documents
|
||||
- `passport_australia`, `passport_us`, `passport_uk`, `passport_germany`, etc.
|
||||
- `us_ssn`, `us_ssn_no_dash`
|
||||
- `au_tfn`, `au_abn`, `au_medicare`
|
||||
- `nl_bsn_contextual`
|
||||
- `br_cpf`, `br_rg`, `br_cnpj`
|
||||
|
||||
### Financial
|
||||
- `visa`, `mastercard`, `amex`, `discover`, `credit_card`
|
||||
- `iban`
|
||||
|
||||
### Contact Information
|
||||
- `email`
|
||||
- `us_phone`, `br_phone_landline`, `br_phone_mobile`
|
||||
- `street_address`
|
||||
- `br_cep` (Brazilian postal code)
|
||||
|
||||
### Credentials
|
||||
- `aws_access_key`, `aws_secret_key`
|
||||
- `github_token`
|
||||
- `slack_token`
|
||||
- `generic_api_key`
|
||||
|
||||
### Network
|
||||
- `ipv4`, `ipv6`
|
||||
|
||||
### Protected Class
|
||||
- `gender_sexual_orientation`
|
||||
- `race_ethnicity_national_origin`
|
||||
- `religion`
|
||||
- `age_discrimination`
|
||||
- `disability`
|
||||
- `marital_family_status`
|
||||
- `military_status`
|
||||
- `public_assistance`
|
||||
|
||||
See the [full patterns list](https://github.com/BerriAI/litellm/blob/main/litellm/proxy/guardrails/guardrail_hooks/litellm_content_filter/patterns.json) for all available patterns.
|
||||
|
||||
## Related Docs
|
||||
|
||||
- [Guardrail Policies](./guardrail_policies)
|
||||
- [Policy Tags](./policy_tags)
|
||||
- [Content Filter Patterns](../hooks/content_filter)
|
||||
- [Custom Code Guardrails](../hooks/custom_code)
|
||||
|
|
@ -100,7 +100,7 @@ In cases where encounter other errors when apply Zscaler AI Guard, return exampl
|
|||
}
|
||||
}
|
||||
```
|
||||
## 6. Sending User Information to Zscaler AI Guard for Analysis (Optional)
|
||||
## 6. Sending User Information to Zscaler AI Guard (Optional)
|
||||
If you need to send end-user information to Zscaler AI Guard for analysis, you can set the configuration in the environment variables to True and include the relevant information in custom_headers on Zscaler AI Guard.
|
||||
|
||||
- To send user_api_key_alias:
|
||||
|
|
@ -133,4 +133,30 @@ curl -i http://localhost:8165/v1/chat/completions \
|
|||
"zguard_policy_id": <the custom policy id>
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
## 8. Set Custom Zscaler AI Guard Policy on Litellm Team OR Key Metadata (Optional)
|
||||
In addition to setting `zguard_policy_id` in a request or the configuration file, you can also set it in the metadata for LiteLLM Team or Key. The `zguard_policy_id` is determined using the following order of precedence: request, Key, Team, config file. This logic is illustrated below:
|
||||
```
|
||||
user_api_key_metadata = metadata.get("user_api_key_metadata", {}) or {}
|
||||
team_metadata = metadata.get("team_metadata", {}) or {}
|
||||
policy_id = (
|
||||
metadata.get("zguard_policy_id")
|
||||
if "zguard_policy_id" in metadata
|
||||
else (
|
||||
user_api_key_metadata.get("zguard_policy_id")
|
||||
if "zguard_policy_id" in user_api_key_metadata
|
||||
else (
|
||||
team_metadata.get("zguard_policy_id")
|
||||
if "zguard_policy_id" in team_metadata
|
||||
else self.policy_id
|
||||
)
|
||||
)
|
||||
)
|
||||
```
|
||||
You can leverage this feature to apply multiple policies configured on the Zscaler AI Guard (ZGuard) to traffic from different applications. (Note: It is recommended to map policies using either Team or Key metadata, but not a mix of both.)
|
||||
|
||||
Example set in Team/Key Metadata, you can set From UI:
|
||||
```
|
||||
{"zguard_policy_id": 100}
|
||||
```
|
||||
|
|
@ -250,11 +250,133 @@ The migrate deploy command:
|
|||
|
||||
### Read-only File System
|
||||
|
||||
If you see a `Permission denied` error, it means the LiteLLM pod is running with a read-only file system.
|
||||
Running LiteLLM with `readOnlyRootFilesystem: true` is a Kubernetes security best practice that prevents container processes from writing to the root filesystem. LiteLLM fully supports this configuration.
|
||||
|
||||
To fix this, just set `LITELLM_MIGRATION_DIR="/path/to/writeable/directory"` in your environment.
|
||||
#### Quick Fix for Permission Errors
|
||||
|
||||
LiteLLM will use this directory to write migration files.
|
||||
If you see a `Permission denied` error, it means the LiteLLM pod is running with a read-only file system. LiteLLM needs writable directories for:
|
||||
- **Database migrations**: Set `LITELLM_MIGRATION_DIR="/path/to/writable/directory"`
|
||||
- **Admin UI**: Set `LITELLM_UI_PATH="/path/to/writable/directory"`
|
||||
- **UI assets/logos**: Set `LITELLM_ASSETS_PATH="/path/to/writable/directory"`
|
||||
|
||||
#### Complete Read-Only Filesystem Setup (Kubernetes)
|
||||
|
||||
For production deployments with enhanced security, use this configuration:
|
||||
|
||||
**Option 1: Using EmptyDir Volumes with InitContainer (Recommended)**
|
||||
|
||||
This approach copies the pre-built UI from the Docker image to writable emptyDir volumes at pod startup.
|
||||
|
||||
```yaml
|
||||
apiVersion: apps/v1
|
||||
kind: Deployment
|
||||
metadata:
|
||||
name: litellm-proxy
|
||||
spec:
|
||||
template:
|
||||
spec:
|
||||
initContainers:
|
||||
- name: setup-ui
|
||||
image: ghcr.io/berriai/litellm:main-stable
|
||||
command:
|
||||
- sh
|
||||
- -c
|
||||
- |
|
||||
cp -r /var/lib/litellm/ui/* /app/var/litellm/ui/ && \
|
||||
cp -r /var/lib/litellm/assets/* /app/var/litellm/assets/
|
||||
volumeMounts:
|
||||
- name: ui-volume
|
||||
mountPath: /app/var/litellm/ui
|
||||
- name: assets-volume
|
||||
mountPath: /app/var/litellm/assets
|
||||
|
||||
containers:
|
||||
- name: litellm
|
||||
image: ghcr.io/berriai/litellm:main-stable
|
||||
env:
|
||||
- name: LITELLM_NON_ROOT
|
||||
value: "true"
|
||||
- name: LITELLM_UI_PATH
|
||||
value: "/app/var/litellm/ui"
|
||||
- name: LITELLM_ASSETS_PATH
|
||||
value: "/app/var/litellm/assets"
|
||||
- name: LITELLM_MIGRATION_DIR
|
||||
value: "/app/migrations"
|
||||
- name: PRISMA_BINARY_CACHE_DIR
|
||||
value: "/app/cache/prisma-python/binaries"
|
||||
- name: XDG_CACHE_HOME
|
||||
value: "/app/cache"
|
||||
securityContext:
|
||||
readOnlyRootFilesystem: true
|
||||
runAsNonRoot: true
|
||||
runAsUser: 101
|
||||
capabilities:
|
||||
drop:
|
||||
- ALL
|
||||
volumeMounts:
|
||||
- name: config
|
||||
mountPath: /app/config.yaml
|
||||
subPath: config.yaml
|
||||
readOnly: true
|
||||
- name: ui-volume
|
||||
mountPath: /app/var/litellm/ui
|
||||
- name: assets-volume
|
||||
mountPath: /app/var/litellm/assets
|
||||
- name: cache
|
||||
mountPath: /app/cache
|
||||
- name: migrations
|
||||
mountPath: /app/migrations
|
||||
|
||||
volumes:
|
||||
- name: config
|
||||
configMap:
|
||||
name: litellm-config
|
||||
- name: ui-volume
|
||||
emptyDir:
|
||||
sizeLimit: 100Mi
|
||||
- name: assets-volume
|
||||
emptyDir:
|
||||
sizeLimit: 10Mi
|
||||
- name: cache
|
||||
emptyDir:
|
||||
sizeLimit: 500Mi
|
||||
- name: migrations
|
||||
emptyDir:
|
||||
sizeLimit: 64Mi
|
||||
```
|
||||
|
||||
**Option 2: Without UI (API-only deployment)**
|
||||
|
||||
If you don't need the admin UI, you can run with minimal configuration:
|
||||
|
||||
```yaml
|
||||
env:
|
||||
- name: LITELLM_NON_ROOT
|
||||
value: "true"
|
||||
- name: LITELLM_MIGRATION_DIR
|
||||
value: "/app/migrations"
|
||||
securityContext:
|
||||
readOnlyRootFilesystem: true
|
||||
```
|
||||
|
||||
The proxy will log a warning about the UI but API endpoints will work normally.
|
||||
|
||||
#### Environment Variables for Read-Only Filesystems
|
||||
|
||||
| Variable | Purpose | Default |
|
||||
|----------|---------|---------|
|
||||
| `LITELLM_UI_PATH` | Admin UI directory | `/var/lib/litellm/ui` (Docker) |
|
||||
| `LITELLM_ASSETS_PATH` | UI assets/logos | `/var/lib/litellm/assets` (Docker) |
|
||||
| `LITELLM_MIGRATION_DIR` | Database migrations | Package directory |
|
||||
| `PRISMA_BINARY_CACHE_DIR` | Prisma binary cache | System default |
|
||||
| `XDG_CACHE_HOME` | General cache directory | System default |
|
||||
|
||||
#### Important Notes
|
||||
|
||||
1. **Migrations**: Always set `LITELLM_MIGRATION_DIR` to a writable emptyDir path
|
||||
2. **Prisma Cache**: Set `PRISMA_BINARY_CACHE_DIR` and `XDG_CACHE_HOME` to writable paths
|
||||
3. **Server Root Path**: If using a custom `server_root_path`, you must pre-process UI files in your Dockerfile as the proxy cannot modify files at runtime with read-only filesystem
|
||||
4. **Automatic Detection**: The UI is automatically detected as pre-restructured if it contains a `.litellm_ui_ready` marker file (created by the official Docker images)
|
||||
|
||||
## 10. Use a Separate Health Check App
|
||||
:::info
|
||||
|
|
|
|||
43
docs/my-website/docs/proxy/pyroscope_profiling.md
Normal file
|
|
@ -0,0 +1,43 @@
|
|||
# Grafana Pyroscope CPU profiling
|
||||
|
||||
LiteLLM proxy can send continuous CPU profiles to [Grafana Pyroscope](https://grafana.com/docs/pyroscope/latest/) when enabled via environment variables. This is optional and off by default.
|
||||
|
||||
## Quick start
|
||||
|
||||
1. **Install the optional dependency** (required only when enabling Pyroscope):
|
||||
|
||||
```bash
|
||||
pip install pyroscope-io
|
||||
```
|
||||
|
||||
Or install the proxy extra:
|
||||
|
||||
```bash
|
||||
pip install "litellm[proxy]"
|
||||
```
|
||||
|
||||
2. **Set environment variables** before starting the proxy:
|
||||
|
||||
| Variable | Required | Description |
|
||||
|----------|----------|-------------|
|
||||
| `LITELLM_ENABLE_PYROSCOPE` | Yes (to enable) | Set to `true` to enable Pyroscope profiling. |
|
||||
| `PYROSCOPE_APP_NAME` | Yes (when enabled) | Application name shown in the Pyroscope UI. |
|
||||
| `PYROSCOPE_SERVER_ADDRESS` | Yes (when enabled) | Pyroscope server URL (e.g. `http://localhost:4040`). |
|
||||
| `PYROSCOPE_SAMPLE_RATE` | No | Sample rate (integer). If unset, the pyroscope-io library default is used. |
|
||||
|
||||
3. **Start the proxy**; profiling will begin automatically when the proxy starts.
|
||||
|
||||
```bash
|
||||
export LITELLM_ENABLE_PYROSCOPE=true
|
||||
export PYROSCOPE_APP_NAME=litellm-proxy
|
||||
export PYROSCOPE_SERVER_ADDRESS=http://localhost:4040
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
4. **View profiles** in the Pyroscope (or Grafana) UI and select your `PYROSCOPE_APP_NAME`.
|
||||
|
||||
## Notes
|
||||
|
||||
- **Optional dependency**: `pyroscope-io` is an optional dependency. If it is not installed and `LITELLM_ENABLE_PYROSCOPE=true`, the proxy will log a warning and continue without profiling.
|
||||
- **Platform support**: The `pyroscope-io` package uses a native extension and is not available on all platforms (e.g. Windows is excluded by the package).
|
||||
- **Other settings**: See [Configuration settings](/proxy/config_settings) for all proxy environment variables.
|
||||
128
docs/my-website/docs/proxy/sync_anthropic_beta_headers.md
Normal file
|
|
@ -0,0 +1,128 @@
|
|||
# Auto Sync Anthropic Beta Headers
|
||||
|
||||
Automatically keep your Anthropic beta headers configuration up to date without restarting your service. **This allows you to support new Anthropic beta features across all providers without restarting your service.**
|
||||
|
||||
## Overview
|
||||
|
||||
When Anthropic releases new beta features (e.g., new tool capabilities, extended context windows), you typically need to restart your LiteLLM service to get the latest beta header mappings for different providers (Anthropic, Bedrock, Vertex AI, Azure AI).
|
||||
|
||||
With auto-sync, LiteLLM automatically pulls the latest configuration from GitHub's [`anthropic_beta_headers_config.json`](https://github.com/BerriAI/litellm/blob/main/litellm/anthropic_beta_headers_config.json) without requiring a restart. This means:
|
||||
|
||||
- **Zero downtime** when new beta features are released
|
||||
- **Always up-to-date** provider support mappings
|
||||
- **Automatic updates** - set it once and forget it
|
||||
|
||||
## Quick Start
|
||||
|
||||
**Manual sync:**
|
||||
```bash
|
||||
curl -X POST "https://your-proxy-url/reload/anthropic_beta_headers" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN" \
|
||||
-H "Content-Type: application/json"
|
||||
```
|
||||
|
||||
**Automatic sync every 24 hours:**
|
||||
```bash
|
||||
curl -X POST "https://your-proxy-url/schedule/anthropic_beta_headers_reload?hours=24" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN" \
|
||||
-H "Content-Type: application/json"
|
||||
```
|
||||
|
||||
## API Endpoints
|
||||
|
||||
| Endpoint | Method | Description |
|
||||
|----------|--------|-------------|
|
||||
| `/reload/anthropic_beta_headers` | POST | Manual sync |
|
||||
| `/schedule/anthropic_beta_headers_reload?hours={hours}` | POST | Schedule periodic sync |
|
||||
| `/schedule/anthropic_beta_headers_reload` | DELETE | Cancel scheduled sync |
|
||||
| `/schedule/anthropic_beta_headers_reload/status` | GET | Check sync status |
|
||||
|
||||
**Authentication:** Requires admin role or master key
|
||||
|
||||
## Python Example
|
||||
|
||||
```python
|
||||
import requests
|
||||
|
||||
def sync_anthropic_beta_headers(proxy_url, admin_token):
|
||||
response = requests.post(
|
||||
f"{proxy_url}/reload/anthropic_beta_headers",
|
||||
headers={"Authorization": f"Bearer {admin_token}"}
|
||||
)
|
||||
return response.json()
|
||||
|
||||
# Usage
|
||||
result = sync_anthropic_beta_headers("https://your-proxy-url", "your-admin-token")
|
||||
print(result['message'])
|
||||
```
|
||||
|
||||
## Configuration
|
||||
|
||||
**Custom beta headers config URL:**
|
||||
```bash
|
||||
export LITELLM_ANTHROPIC_BETA_HEADERS_URL="https://raw.githubusercontent.com/BerriAI/litellm/main/litellm/anthropic_beta_headers_config.json"
|
||||
```
|
||||
|
||||
**Use local beta headers config:**
|
||||
```bash
|
||||
export LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS=True
|
||||
```
|
||||
|
||||
## Scheduling Automatic Reloads
|
||||
|
||||
Schedule automatic reloads to ensure your proxy always has the latest beta header mappings:
|
||||
|
||||
```bash
|
||||
# Reload every 24 hours
|
||||
curl -X POST "https://your-proxy-url/schedule/anthropic_beta_headers_reload?hours=24" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
**Check reload status:**
|
||||
```bash
|
||||
curl -X GET "https://your-proxy-url/schedule/anthropic_beta_headers_reload/status" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
**Response:**
|
||||
```json
|
||||
{
|
||||
"scheduled": true,
|
||||
"interval_hours": 24,
|
||||
"last_run": "2026-02-13T10:00:00",
|
||||
"next_run": "2026-02-14T10:00:00"
|
||||
}
|
||||
```
|
||||
|
||||
**Cancel scheduled reload:**
|
||||
```bash
|
||||
curl -X DELETE "https://your-proxy-url/schedule/anthropic_beta_headers_reload" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
## Environment Variables
|
||||
|
||||
| Variable | Description | Default |
|
||||
|----------|-------------|---------|
|
||||
| `LITELLM_ANTHROPIC_BETA_HEADERS_URL` | URL to fetch beta headers config from | GitHub main branch |
|
||||
| `LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS` | Set to `True` to use local config only | `False` |
|
||||
|
||||
## How It Works
|
||||
|
||||
1. **Initial Load:** On startup, LiteLLM loads the beta headers configuration from the remote URL (or local file if configured)
|
||||
2. **Caching:** The configuration is cached in memory to avoid repeated fetches on every request
|
||||
3. **Scheduled Reload:** If configured, the proxy checks every 10 seconds whether it's time to reload based on your schedule
|
||||
4. **Manual Reload:** You can trigger an immediate reload via the API endpoint
|
||||
5. **Multi-Pod Support:** In multi-pod deployments, the reload configuration is stored in the database so all pods stay in sync
|
||||
|
||||
## Benefits
|
||||
|
||||
- **No Restarts Required:** Add support for new Anthropic beta features without downtime
|
||||
- **Provider Compatibility:** Automatically get updated mappings for Bedrock, Vertex AI, Azure AI, etc.
|
||||
- **Performance:** Configuration is cached and only reloaded when needed
|
||||
- **Reliability:** Falls back to local configuration if remote fetch fails
|
||||
|
||||
## Related
|
||||
|
||||
- [Model Cost Map Sync](./sync_models_github.md) - Auto-sync model pricing data
|
||||
- [Anthropic Beta Headers](../completion/anthropic.md#beta-features) - Using Anthropic beta features
|
||||
130
docs/my-website/docs/proxy/ui_team_soft_budget_alerts.md
Normal file
|
|
@ -0,0 +1,130 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Team Soft Budget Alerts
|
||||
|
||||
Set a soft budget on a team and get email alerts when spending crosses the threshold — without blocking any requests.
|
||||
|
||||
## Overview
|
||||
|
||||
A **soft budget** is a spending threshold that triggers email notifications when exceeded, but **does not block requests**. This is different from a hard budget (`max_budget`), which rejects requests once the limit is reached.
|
||||
|
||||
<Image img={require('../../img/ui_team_soft_budget_alerts.png')} />
|
||||
|
||||
Team soft budget alerts let you:
|
||||
|
||||
- **Get notified early** — receive email alerts when a team's spend crosses the soft budget threshold
|
||||
- **Keep requests flowing** — unlike hard budgets, soft budgets never block API calls
|
||||
- **Target specific recipients** — send alerts to specific email addresses (e.g. team leads, finance), not just the team members
|
||||
- **Work without global alerting** — team soft budget alerts are sent via email independently of Slack or other global alerting configuration
|
||||
|
||||
:::warning Email integration required
|
||||
Team soft budget alerts are sent via email. You must have an active email integration (SendGrid, Resend, or SMTP) configured on your proxy for alerts to be delivered. See [Email Notifications](./email.md) for setup instructions.
|
||||
:::
|
||||
|
||||
:::info Automatically active
|
||||
Team soft budget alerts are **automatically active** once you configure a soft budget and at least one alerting email on a team. No additional proxy configuration or restart is needed — alerts are checked on every request.
|
||||
:::
|
||||
|
||||
## How It Works
|
||||
|
||||
On every API request made with a key belonging to a team, the proxy checks:
|
||||
|
||||
1. Does the team have a `soft_budget` set?
|
||||
2. Is the team's current `spend` >= the `soft_budget`?
|
||||
3. Are there any emails configured in `soft_budget_alerting_emails`?
|
||||
|
||||
If all three conditions are met, an email alert is sent to the configured recipients. Alerts are **deduplicated** so the same alert is only sent once within a 24-hour window.
|
||||
|
||||
## How to Set Up Team Soft Budget Alerts
|
||||
|
||||
### 1. Navigate to the Admin UI
|
||||
|
||||
Go to the Admin UI (e.g. `http://localhost:4000/ui` or your `PROXY_BASE_URL/ui`).
|
||||
|
||||
|
||||
|
||||
### 2. Go to Teams
|
||||
|
||||
Click **Teams** in the sidebar.
|
||||
|
||||
|
||||
|
||||
### 3. Select a team
|
||||
|
||||
Click on the team you want to configure soft budget alerts for.
|
||||
|
||||
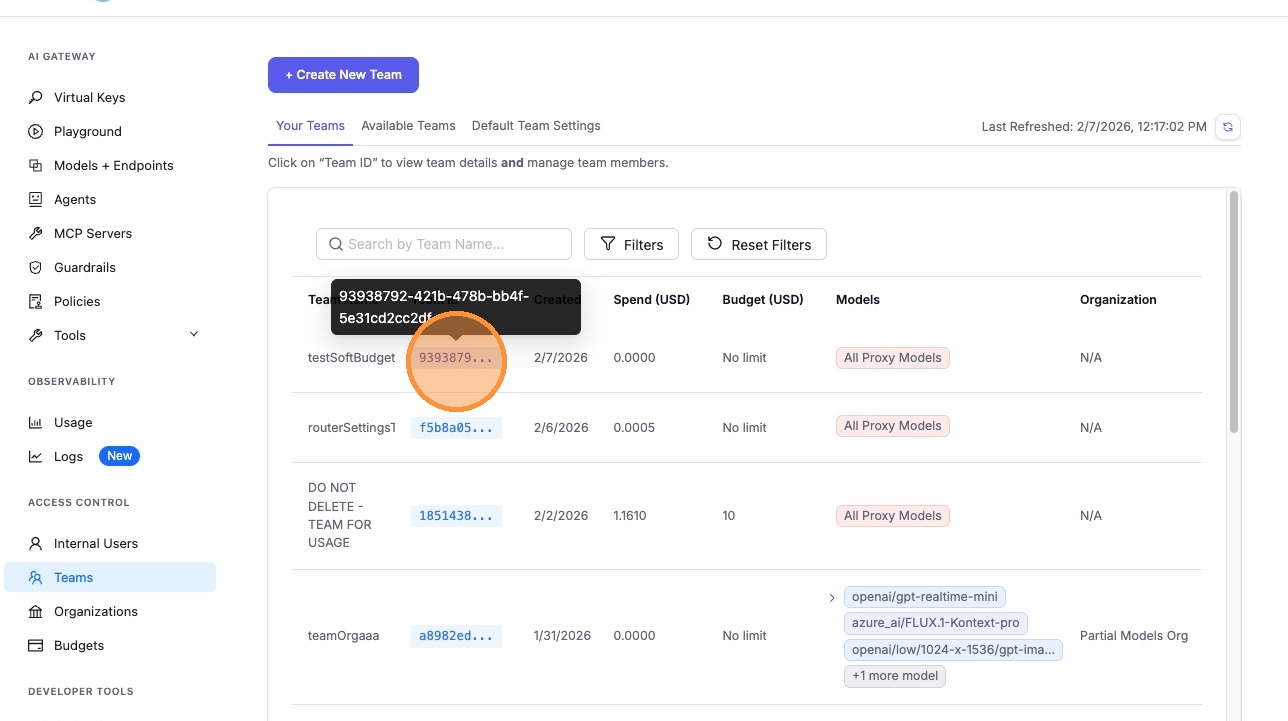
|
||||
|
||||
### 4. Open team Settings
|
||||
|
||||
Click the **Settings** tab to view the team's configuration.
|
||||
|
||||
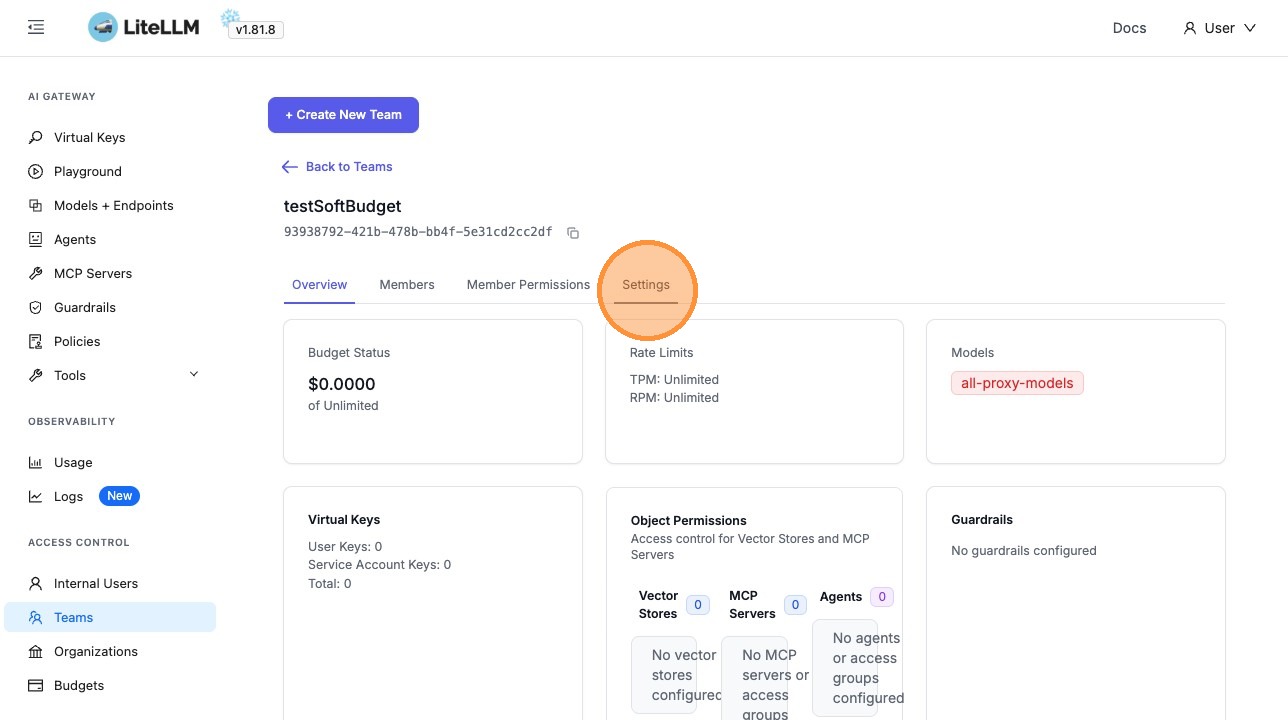
|
||||
|
||||
### 5. Edit Settings
|
||||
|
||||
Click **Edit Settings** to modify the team's budget configuration.
|
||||
|
||||
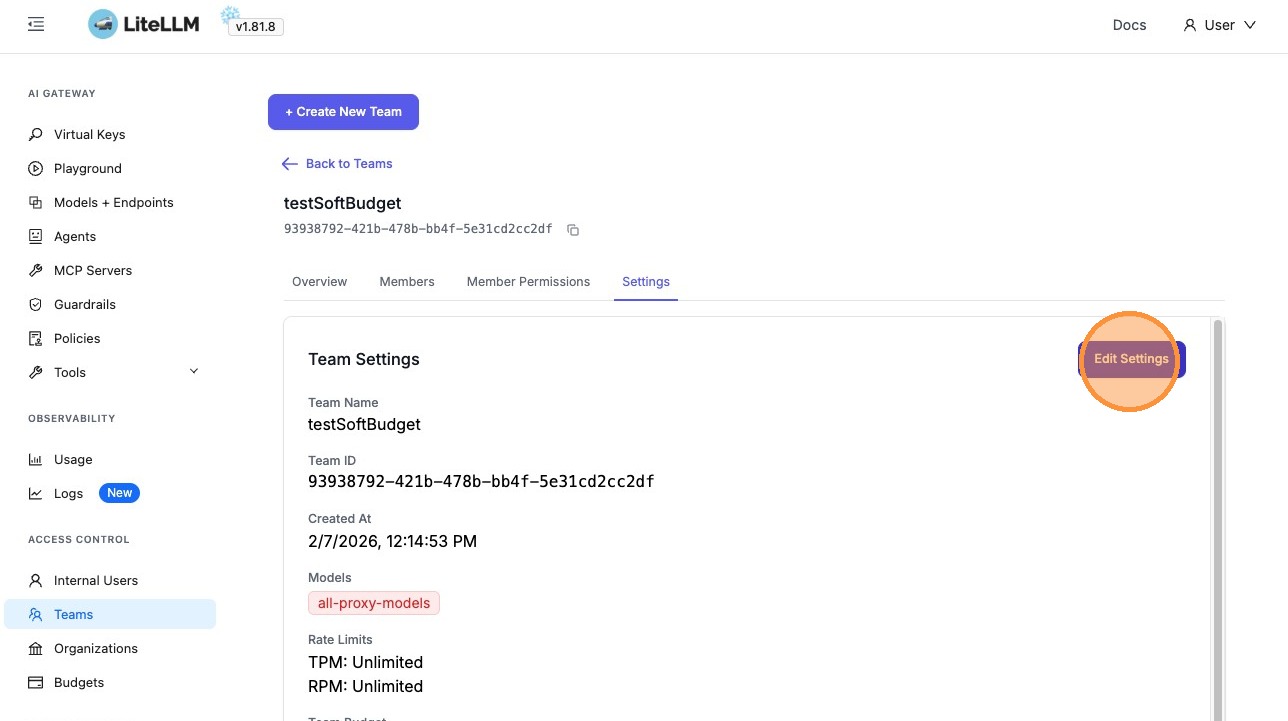
|
||||
|
||||
### 6. Set the Soft Budget
|
||||
|
||||
Click the **Soft Budget (USD)** field and enter your desired threshold. For example, enter `0.01` for testing or a higher value like `500` for production.
|
||||
|
||||
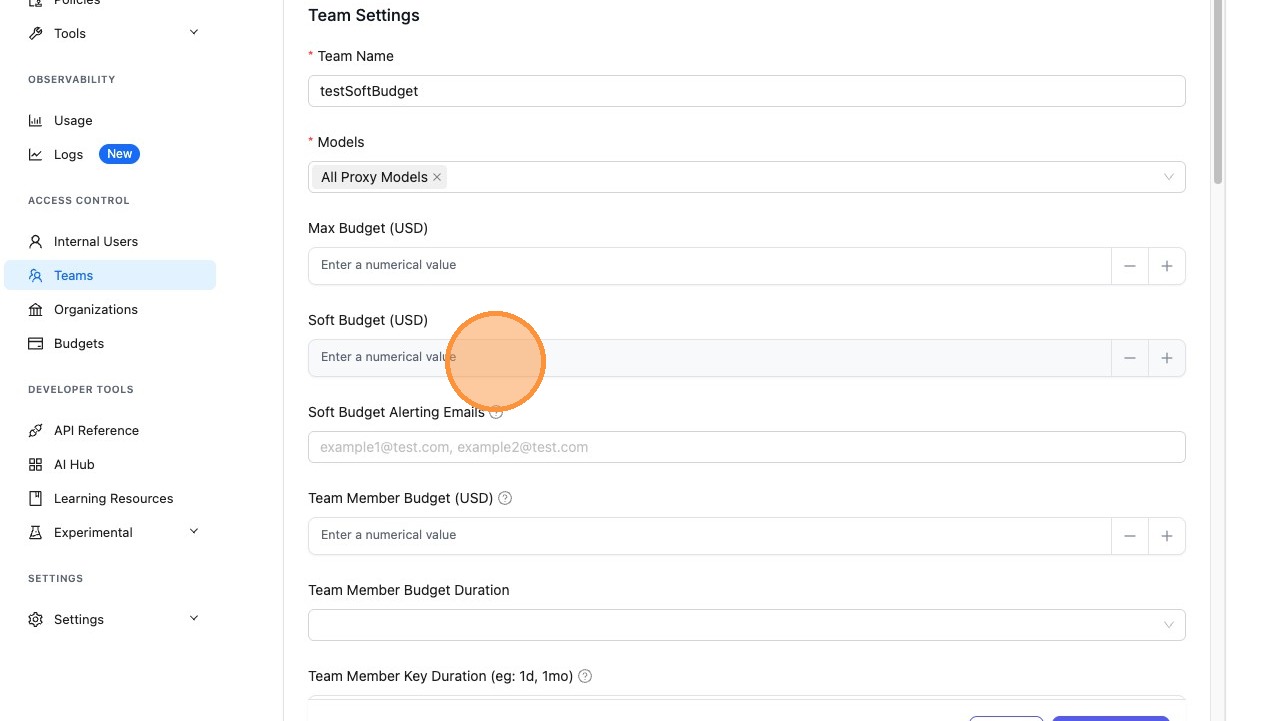
|
||||
|
||||
### 7. Add alerting emails
|
||||
|
||||
Click the **Soft Budget Alerting Emails** field and enter one or more comma-separated email addresses that should receive the alert.
|
||||
|
||||
|
||||
|
||||
### 8. Save Changes
|
||||
|
||||
Click **Save Changes**. The soft budget alert is now active — no proxy restart required.
|
||||
|
||||
|
||||
|
||||
### 9. Verify: email alert received
|
||||
|
||||
Once the team's spend crosses the soft budget, an email alert is sent to the configured recipients. Below is an example of the alert email:
|
||||
|
||||
<Image img={require('../../img/ui_team_soft_budget_email_example.png')} />
|
||||
|
||||
## Settings Reference
|
||||
|
||||
| Setting | Description |
|
||||
| ------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------- |
|
||||
| **Soft Budget (USD)** | The spending threshold that triggers an email alert. Requests are **not** blocked when this limit is exceeded. |
|
||||
| **Soft Budget Alerting Emails** | Comma-separated email addresses that receive the alert when the soft budget is crossed. At least one email is required for alerts to be sent. |
|
||||
|
||||
:::tip Soft Budget vs. Max Budget
|
||||
|
||||
- **Soft Budget**: Advisory threshold — sends email alerts but does **not** block requests.
|
||||
- **Max Budget**: Hard limit — blocks requests once the budget is exceeded.
|
||||
|
||||
You can set both on the same team to get early warnings (soft) and a hard stop (max).
|
||||
:::
|
||||
|
||||
## API Configuration
|
||||
|
||||
You can also configure team soft budgets via the API when creating or updating a team:
|
||||
|
||||
```bash
|
||||
curl -X POST 'http://localhost:4000/team/update' \
|
||||
--header 'Authorization: Bearer sk-1234' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"team_id": "your-team-id",
|
||||
"soft_budget": 500.00,
|
||||
"metadata": {
|
||||
"soft_budget_alerting_emails": ["lead@example.com", "finance@example.com"]
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
## Related Documentation
|
||||
|
||||
- [Email Notifications](./email.md) – Configure email integrations (Resend, SMTP) for LiteLLM Proxy
|
||||
- [Alerting](./alerting.md) – Set up Slack and other alerting channels
|
||||
- [Cost Tracking](./cost_tracking.md) – Track and manage spend across teams, keys, and users
|
||||
333
docs/my-website/docs/proxy_auth.md
Normal file
|
|
@ -0,0 +1,333 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# SDK Proxy Authentication (OAuth2/JWT Auto-Refresh)
|
||||
|
||||
Automatically obtain and refresh OAuth2/JWT tokens when using the LiteLLM Python SDK with a LiteLLM Proxy that requires JWT authentication.
|
||||
|
||||
## Overview
|
||||
|
||||
When your LiteLLM Proxy is protected by an OAuth2/OIDC provider (Azure AD, Keycloak, Okta, Auth0, etc.), your SDK clients need valid JWT tokens for every request. Instead of manually managing token lifecycle, `litellm.proxy_auth` handles this automatically:
|
||||
|
||||
- Obtains tokens from your identity provider
|
||||
- Caches tokens to avoid unnecessary requests
|
||||
- Refreshes tokens before they expire (60-second buffer)
|
||||
- Injects `Authorization: Bearer <token>` headers into every request
|
||||
|
||||
## Quick Start
|
||||
|
||||
### Azure AD
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="default" label="DefaultAzureCredential">
|
||||
|
||||
Uses the [DefaultAzureCredential](https://learn.microsoft.com/en-us/python/api/azure-identity/azure.identity.defaultazurecredential) chain (environment variables, managed identity, Azure CLI, etc.):
|
||||
|
||||
```python
|
||||
import litellm
|
||||
from litellm.proxy_auth import AzureADCredential, ProxyAuthHandler
|
||||
|
||||
# One-time setup
|
||||
litellm.proxy_auth = ProxyAuthHandler(
|
||||
credential=AzureADCredential(), # uses DefaultAzureCredential
|
||||
scope="api://my-litellm-proxy/.default"
|
||||
)
|
||||
litellm.api_base = "https://my-proxy.example.com"
|
||||
|
||||
# All requests now include Authorization headers automatically
|
||||
response = litellm.completion(
|
||||
model="gpt-4",
|
||||
messages=[{"role": "user", "content": "Hello!"}]
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="client-secret" label="ClientSecretCredential">
|
||||
|
||||
Use a specific Azure AD app registration:
|
||||
|
||||
```python
|
||||
import litellm
|
||||
from azure.identity import ClientSecretCredential
|
||||
from litellm.proxy_auth import AzureADCredential, ProxyAuthHandler
|
||||
|
||||
azure_cred = ClientSecretCredential(
|
||||
tenant_id="your-tenant-id",
|
||||
client_id="your-client-id",
|
||||
client_secret="your-client-secret"
|
||||
)
|
||||
|
||||
litellm.proxy_auth = ProxyAuthHandler(
|
||||
credential=AzureADCredential(credential=azure_cred),
|
||||
scope="api://my-litellm-proxy/.default"
|
||||
)
|
||||
litellm.api_base = "https://my-proxy.example.com"
|
||||
|
||||
response = litellm.completion(
|
||||
model="gpt-4",
|
||||
messages=[{"role": "user", "content": "Hello!"}]
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
**Required package:** `pip install azure-identity`
|
||||
|
||||
### Generic OAuth2 (Okta, Auth0, Keycloak, etc.)
|
||||
|
||||
Works with any OAuth2 provider that supports the `client_credentials` grant type:
|
||||
|
||||
```python
|
||||
import litellm
|
||||
from litellm.proxy_auth import GenericOAuth2Credential, ProxyAuthHandler
|
||||
|
||||
litellm.proxy_auth = ProxyAuthHandler(
|
||||
credential=GenericOAuth2Credential(
|
||||
client_id="your-client-id",
|
||||
client_secret="your-client-secret",
|
||||
token_url="https://your-idp.example.com/oauth2/token"
|
||||
),
|
||||
scope="litellm_proxy_api"
|
||||
)
|
||||
litellm.api_base = "https://my-proxy.example.com"
|
||||
|
||||
response = litellm.completion(
|
||||
model="gpt-4",
|
||||
messages=[{"role": "user", "content": "Hello!"}]
|
||||
)
|
||||
```
|
||||
|
||||
### Custom Credential Provider
|
||||
|
||||
Implement the `TokenCredential` protocol to use any authentication mechanism:
|
||||
|
||||
```python
|
||||
import time
|
||||
import litellm
|
||||
from litellm.proxy_auth import AccessToken, ProxyAuthHandler
|
||||
|
||||
class MyCustomCredential:
|
||||
"""Any class with a get_token(scope) -> AccessToken method works."""
|
||||
|
||||
def get_token(self, scope: str) -> AccessToken:
|
||||
# Your custom logic to obtain a token
|
||||
token = my_auth_system.get_jwt(scope=scope)
|
||||
return AccessToken(
|
||||
token=token,
|
||||
expires_on=int(time.time()) + 3600
|
||||
)
|
||||
|
||||
litellm.proxy_auth = ProxyAuthHandler(
|
||||
credential=MyCustomCredential(),
|
||||
scope="my-scope"
|
||||
)
|
||||
```
|
||||
|
||||
## Supported Endpoints
|
||||
|
||||
Auth headers are automatically injected for:
|
||||
|
||||
| Endpoint | Function |
|
||||
|----------|----------|
|
||||
| Chat Completions | `litellm.completion()` / `litellm.acompletion()` |
|
||||
| Embeddings | `litellm.embedding()` / `litellm.aembedding()` |
|
||||
|
||||
## How It Works
|
||||
|
||||
```
|
||||
┌──────────┐ ┌──────────────────┐ ┌──────────────┐ ┌──────────────┐
|
||||
│ Your │ │ ProxyAuthHandler │ │ Identity │ │ LiteLLM │
|
||||
│ Code │────▶│ (token cache) │────▶│ Provider │ │ Proxy │
|
||||
│ │ │ │◀────│ (Azure AD, │ │ │
|
||||
│ │ │ │ │ Okta, etc) │ │ │
|
||||
│ │ └────────┬─────────┘ └──────────────┘ │ │
|
||||
│ │ │ Authorization: Bearer <token> │ │
|
||||
│ │──────────────┼───────────────────────────────────▶│ │
|
||||
│ │◀─────────────┼────────────────────────────────────│ │
|
||||
└──────────┘ │ └──────────────┘
|
||||
```
|
||||
|
||||
1. You set `litellm.proxy_auth` once at startup
|
||||
2. On each SDK call (`completion()`, `embedding()`), the handler checks its cached token
|
||||
3. If the token is missing or expires within 60 seconds, it requests a new one from your identity provider
|
||||
4. The `Authorization: Bearer <token>` header is injected into the request
|
||||
5. If token retrieval fails, a warning is logged and the request proceeds without auth headers
|
||||
|
||||
## API Reference
|
||||
|
||||
### ProxyAuthHandler
|
||||
|
||||
The main handler that manages the token lifecycle.
|
||||
|
||||
```python
|
||||
from litellm.proxy_auth import ProxyAuthHandler
|
||||
|
||||
handler = ProxyAuthHandler(
|
||||
credential=<TokenCredential>, # required - credential provider
|
||||
scope="<oauth2-scope>" # required - OAuth2 scope to request
|
||||
)
|
||||
```
|
||||
|
||||
| Parameter | Type | Required | Description |
|
||||
|-----------|------|----------|-------------|
|
||||
| `credential` | `TokenCredential` | Yes | A credential provider (AzureADCredential, GenericOAuth2Credential, or custom) |
|
||||
| `scope` | `str` | Yes | The OAuth2 scope to request tokens for |
|
||||
|
||||
**Methods:**
|
||||
|
||||
| Method | Returns | Description |
|
||||
|--------|---------|-------------|
|
||||
| `get_token()` | `AccessToken` | Get a valid token, refreshing if needed |
|
||||
| `get_auth_headers()` | `dict` | Get `{"Authorization": "Bearer <token>"}` headers |
|
||||
|
||||
### AzureADCredential
|
||||
|
||||
Wraps any `azure-identity` credential with lazy initialization.
|
||||
|
||||
```python
|
||||
from litellm.proxy_auth import AzureADCredential
|
||||
|
||||
# Uses DefaultAzureCredential (recommended)
|
||||
cred = AzureADCredential()
|
||||
|
||||
# Or wrap a specific azure-identity credential
|
||||
from azure.identity import ManagedIdentityCredential
|
||||
cred = AzureADCredential(credential=ManagedIdentityCredential())
|
||||
```
|
||||
|
||||
| Parameter | Type | Required | Description |
|
||||
|-----------|------|----------|-------------|
|
||||
| `credential` | Azure `TokenCredential` | No | An azure-identity credential. If `None`, uses `DefaultAzureCredential` |
|
||||
|
||||
### GenericOAuth2Credential
|
||||
|
||||
Standard OAuth2 client credentials flow for any provider.
|
||||
|
||||
```python
|
||||
from litellm.proxy_auth import GenericOAuth2Credential
|
||||
|
||||
cred = GenericOAuth2Credential(
|
||||
client_id="your-client-id",
|
||||
client_secret="your-client-secret",
|
||||
token_url="https://your-idp.com/oauth2/token"
|
||||
)
|
||||
```
|
||||
|
||||
| Parameter | Type | Required | Description |
|
||||
|-----------|------|----------|-------------|
|
||||
| `client_id` | `str` | Yes | OAuth2 client ID |
|
||||
| `client_secret` | `str` | Yes | OAuth2 client secret |
|
||||
| `token_url` | `str` | Yes | Token endpoint URL |
|
||||
|
||||
### AccessToken
|
||||
|
||||
Dataclass representing an OAuth2 access token.
|
||||
|
||||
```python
|
||||
from litellm.proxy_auth import AccessToken
|
||||
|
||||
token = AccessToken(
|
||||
token="eyJhbG...", # JWT string
|
||||
expires_on=1234567890 # Unix timestamp
|
||||
)
|
||||
```
|
||||
|
||||
### TokenCredential Protocol
|
||||
|
||||
Any class implementing this protocol can be used as a credential provider:
|
||||
|
||||
```python
|
||||
from litellm.proxy_auth import AccessToken
|
||||
|
||||
class MyCredential:
|
||||
def get_token(self, scope: str) -> AccessToken:
|
||||
...
|
||||
```
|
||||
|
||||
## Provider-Specific Examples
|
||||
|
||||
### Keycloak
|
||||
|
||||
```python
|
||||
from litellm.proxy_auth import GenericOAuth2Credential, ProxyAuthHandler
|
||||
|
||||
litellm.proxy_auth = ProxyAuthHandler(
|
||||
credential=GenericOAuth2Credential(
|
||||
client_id="litellm-client",
|
||||
client_secret="your-keycloak-client-secret",
|
||||
token_url="https://keycloak.example.com/realms/your-realm/protocol/openid-connect/token"
|
||||
),
|
||||
scope="openid"
|
||||
)
|
||||
```
|
||||
|
||||
### Okta
|
||||
|
||||
```python
|
||||
from litellm.proxy_auth import GenericOAuth2Credential, ProxyAuthHandler
|
||||
|
||||
litellm.proxy_auth = ProxyAuthHandler(
|
||||
credential=GenericOAuth2Credential(
|
||||
client_id="your-okta-client-id",
|
||||
client_secret="your-okta-client-secret",
|
||||
token_url="https://your-org.okta.com/oauth2/default/v1/token"
|
||||
),
|
||||
scope="litellm_api"
|
||||
)
|
||||
```
|
||||
|
||||
### Auth0
|
||||
|
||||
```python
|
||||
from litellm.proxy_auth import GenericOAuth2Credential, ProxyAuthHandler
|
||||
|
||||
litellm.proxy_auth = ProxyAuthHandler(
|
||||
credential=GenericOAuth2Credential(
|
||||
client_id="your-auth0-client-id",
|
||||
client_secret="your-auth0-client-secret",
|
||||
token_url="https://your-tenant.auth0.com/oauth/token"
|
||||
),
|
||||
scope="https://my-proxy.example.com/api"
|
||||
)
|
||||
```
|
||||
|
||||
### Azure AD with Managed Identity
|
||||
|
||||
```python
|
||||
from azure.identity import ManagedIdentityCredential
|
||||
from litellm.proxy_auth import AzureADCredential, ProxyAuthHandler
|
||||
|
||||
litellm.proxy_auth = ProxyAuthHandler(
|
||||
credential=AzureADCredential(
|
||||
credential=ManagedIdentityCredential()
|
||||
),
|
||||
scope="api://my-litellm-proxy/.default"
|
||||
)
|
||||
```
|
||||
|
||||
## Combining with `use_litellm_proxy`
|
||||
|
||||
You can use `proxy_auth` together with [`use_litellm_proxy`](./providers/litellm_proxy#send-all-sdk-requests-to-litellm-proxy) to route all SDK requests through an authenticated proxy:
|
||||
|
||||
```python
|
||||
import os
|
||||
import litellm
|
||||
from litellm.proxy_auth import AzureADCredential, ProxyAuthHandler
|
||||
|
||||
# Route all requests through the proxy
|
||||
os.environ["LITELLM_PROXY_API_BASE"] = "https://my-proxy.example.com"
|
||||
litellm.use_litellm_proxy = True
|
||||
|
||||
# Authenticate with OAuth2/JWT
|
||||
litellm.proxy_auth = ProxyAuthHandler(
|
||||
credential=AzureADCredential(),
|
||||
scope="api://my-litellm-proxy/.default"
|
||||
)
|
||||
|
||||
# This request goes through the proxy with automatic JWT auth
|
||||
response = litellm.completion(
|
||||
model="vertex_ai/gemini-2.0-flash-001",
|
||||
messages=[{"role": "user", "content": "Hello!"}]
|
||||
)
|
||||
```
|
||||
|
|
@ -3,11 +3,12 @@ import TabItem from '@theme/TabItem';
|
|||
|
||||
# /realtime
|
||||
|
||||
Use this to loadbalance across Azure + OpenAI.
|
||||
Use this to loadbalance across Azure + OpenAI + xAI and more.
|
||||
|
||||
Supported Providers:
|
||||
- OpenAI
|
||||
- Azure
|
||||
- xAI ([see full docs](/docs/providers/xai_realtime))
|
||||
- Google AI Studio (Gemini)
|
||||
- Vertex AI
|
||||
- Bedrock
|
||||
|
|
@ -46,6 +47,21 @@ model_list:
|
|||
api_key: os.environ/OPENAI_API_KEY
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="xai" label="xAI Grok Voice Agent">
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: grok-voice-agent
|
||||
litellm_params:
|
||||
model: xai/grok-4-1-fast-non-reasoning
|
||||
api_key: os.environ/XAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
```
|
||||
|
||||
**[See full xAI Realtime documentation →](/docs/providers/xai_realtime)**
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
|
|
|||
|
|
@ -1023,6 +1023,134 @@ curl http://localhost:4000/v1/responses \
|
|||
|
||||
|
||||
|
||||
## Server-side compaction
|
||||
|
||||
For long-running conversations, you can enable **server-side compaction** so that when the rendered context size crosses a threshold, the server automatically runs compaction in-stream and emits a compaction item—no separate `POST /v1/responses/compact` call is required.
|
||||
|
||||
Supported on the OpenAI Responses API when using the `openai` or `azure` provider. Pass `context_management` with a compaction entry and `compact_threshold` (token count; minimum 1000). When the context crosses the threshold, the server compacts in-stream and continues. Chain turns with `previous_response_id` or by appending output items to your next input array. See [OpenAI Compaction guide](https://developers.openai.com/api/docs/guides/compaction) for details.
|
||||
|
||||
For explicit control over when compaction runs, use the standalone compact endpoint (`POST /v1/responses/compact`) instead.
|
||||
|
||||
### Python SDK
|
||||
|
||||
```python showLineNumbers title="Server-side compaction with LiteLLM Python SDK"
|
||||
import litellm
|
||||
|
||||
# Non-streaming: enable compaction when context exceeds 200k tokens
|
||||
response = litellm.responses(
|
||||
model="openai/gpt-4o",
|
||||
input="Your conversation input...",
|
||||
context_management=[{"type": "compaction", "compact_threshold": 200000}],
|
||||
max_output_tokens=1024,
|
||||
)
|
||||
print(response)
|
||||
|
||||
# Streaming: same context_management, compaction runs in-stream if threshold is crossed
|
||||
stream = litellm.responses(
|
||||
model="openai/gpt-4o",
|
||||
input="Your conversation input...",
|
||||
context_management=[{"type": "compaction", "compact_threshold": 200000}],
|
||||
stream=True,
|
||||
)
|
||||
for event in stream:
|
||||
print(event)
|
||||
```
|
||||
|
||||
### LiteLLM Proxy (AI Gateway)
|
||||
|
||||
Use the OpenAI SDK with your proxy as `base_url`, or call the proxy with curl. The proxy forwards `context_management` to the provider.
|
||||
|
||||
**OpenAI Python SDK (proxy as base_url):**
|
||||
|
||||
```python showLineNumbers title="Server-side compaction via LiteLLM Proxy"
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
base_url="http://localhost:4000", # LiteLLM Proxy (AI Gateway)
|
||||
api_key="your-proxy-api-key",
|
||||
)
|
||||
|
||||
response = client.responses.create(
|
||||
model="openai/gpt-4o",
|
||||
input="Your conversation input...",
|
||||
context_management=[{"type": "compaction", "compact_threshold": 200000}],
|
||||
max_output_tokens=1024,
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
**curl (proxy):**
|
||||
|
||||
```bash title="Server-side compaction via curl to LiteLLM Proxy"
|
||||
curl -X POST "http://localhost:4000/v1/responses" \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer your-proxy-api-key" \
|
||||
-d '{
|
||||
"model": "openai/gpt-4o",
|
||||
"input": "Your conversation input...",
|
||||
"context_management": [{"type": "compaction", "compact_threshold": 200000}],
|
||||
"max_output_tokens": 1024
|
||||
}'
|
||||
```
|
||||
|
||||
## Shell tool
|
||||
|
||||
The **Shell tool** lets the model run commands in a hosted container or local runtime (OpenAI Responses API). You pass `tools=[{"type": "shell", "environment": {...}}]`; the `environment` object configures the runtime (e.g. `type: "container_auto"` for auto-provisioned containers). See [OpenAI Shell tool guide](https://developers.openai.com/api/docs/guides/tools-shell) for full options.
|
||||
|
||||
Supported when using the `openai` or `azure` provider with a model that supports the Shell tool.
|
||||
|
||||
### Python SDK
|
||||
|
||||
```python showLineNumbers title="Shell tool with LiteLLM Python SDK"
|
||||
import litellm
|
||||
|
||||
response = litellm.responses(
|
||||
model="openai/gpt-5.2",
|
||||
input="List files in /mnt/data and run python --version.",
|
||||
tools=[{"type": "shell", "environment": {"type": "container_auto"}}],
|
||||
tool_choice="auto",
|
||||
max_output_tokens=1024,
|
||||
)
|
||||
```
|
||||
|
||||
### LiteLLM Proxy (AI Gateway)
|
||||
|
||||
Use the OpenAI SDK with your proxy as `base_url`, or call the proxy with curl. The proxy forwards `tools` (including `type: "shell"`) to the provider.
|
||||
|
||||
**OpenAI Python SDK (proxy as base_url):**
|
||||
|
||||
```python showLineNumbers title="Shell tool via LiteLLM Proxy"
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
base_url="http://localhost:4000",
|
||||
api_key="your-proxy-api-key",
|
||||
)
|
||||
|
||||
response = client.responses.create(
|
||||
model="openai/gpt-5.2",
|
||||
input="List files in /mnt/data.",
|
||||
tools=[{"type": "shell", "environment": {"type": "container_auto"}}],
|
||||
tool_choice="auto",
|
||||
max_output_tokens=1024,
|
||||
)
|
||||
```
|
||||
|
||||
**curl:**
|
||||
|
||||
```bash title="Shell tool via curl to LiteLLM Proxy"
|
||||
curl -X POST "http://localhost:4000/v1/responses" \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer your-proxy-api-key" \
|
||||
-d '{
|
||||
"model": "openai/gpt-5.2",
|
||||
"input": "List files in /mnt/data.",
|
||||
"tools": [{"type": "shell", "environment": {"type": "container_auto"}}],
|
||||
"tool_choice": "auto",
|
||||
"max_output_tokens": 1024
|
||||
}'
|
||||
```
|
||||
|
||||
## Session Management
|
||||
|
||||
LiteLLM Proxy supports session management for all supported models. This allows you to store and fetch conversation history (state) in LiteLLM Proxy.
|
||||
|
|
|
|||
|
|
@ -1,45 +1,43 @@
|
|||
# Troubleshooting & Support
|
||||
|
||||
## Information to Provide When Seeking Help
|
||||
# Issue Reporting
|
||||
|
||||
When reporting issues, please include as much of the following as possible. It's okay if you can't provide everything—especially in production scenarios where the trigger might be unknown. Sharing most of this information will help us assist you more effectively.
|
||||
|
||||
### 1. LiteLLM Configuration File
|
||||
## 1. LiteLLM Configuration File
|
||||
|
||||
Your `config.yaml` file (redact sensitive info like API keys). Include number of workers if not in config.
|
||||
|
||||
### 2. Initialization Command
|
||||
## 2. Initialization Command
|
||||
|
||||
The command used to start LiteLLM (e.g., `litellm --config config.yaml --num_workers 8 --detailed_debug`).
|
||||
|
||||
### 3. LiteLLM Version
|
||||
## 3. LiteLLM Version
|
||||
|
||||
- Current version
|
||||
- Version when the issue first appeared (if different)
|
||||
- Current version
|
||||
- Version when the issue first appeared (if different)
|
||||
- If upgraded, the version changed from → to
|
||||
|
||||
### 4. Environment Variables
|
||||
## 4. Environment Variables
|
||||
|
||||
Non-sensitive environment variables not in your config (e.g., `NUM_WORKERS`, `LITELLM_LOG`, `LITELLM_MODE`). Do not include passwords or API keys.
|
||||
|
||||
### 5. Server Specifications
|
||||
## 5. Server Specifications
|
||||
|
||||
CPU cores, RAM, OS, number of instances/replicas, etc.
|
||||
|
||||
### 6. Database and Redis Usage
|
||||
## 6. Database and Redis Usage
|
||||
|
||||
- **Database:** Using database? (`DATABASE_URL` set), database type and version
|
||||
- **Redis:** Using Redis? Redis version, configuration type (Standalone/Cluster/Sentinel).
|
||||
|
||||
### 7. Endpoints
|
||||
## 7. Endpoints
|
||||
|
||||
The endpoint(s) you're using that are experiencing issues (e.g., `/chat/completions`, `/embeddings`).
|
||||
|
||||
### 8. Request Example
|
||||
## 8. Request Example
|
||||
|
||||
A realistic example of the request causing issues, including expected vs. actual response and any error messages.
|
||||
|
||||
### 9. Error Logs, Stack Traces, and Metrics
|
||||
## 9. Error Logs, Stack Traces, and Metrics
|
||||
|
||||
Full error logs, stack traces, and any images from service metrics (CPU, memory, request rates, etc.) that might help diagnose the issue.
|
||||
|
||||
|
|
@ -57,4 +55,3 @@ Our numbers 📞 +1 (770) 8783-106 / +1 (412) 618-6238
|
|||
Our emails ✉️ ishaan@berri.ai / krrish@berri.ai
|
||||
|
||||
[](https://wa.link/huol9n) [](https://discord.gg/wuPM9dRgDw)
|
||||
|
||||
|
|
|
|||
68
docs/my-website/docs/troubleshoot/max_callbacks.md
Normal file
|
|
@ -0,0 +1,68 @@
|
|||
# MAX_CALLBACKS Limit
|
||||
|
||||
## Error Message
|
||||
|
||||
```
|
||||
Cannot add callback - would exceed MAX_CALLBACKS limit of 30. Current callbacks: 30
|
||||
```
|
||||
|
||||
## What This Means
|
||||
|
||||
LiteLLM limits the number of callbacks that can be registered to prevent performance degradation. Each callback runs on every LLM request, so having too many callbacks can cause exponential CPU usage and slow down your proxy.
|
||||
|
||||
The default limit is **30 callbacks**.
|
||||
|
||||
## When You Might Hit This Limit
|
||||
|
||||
- **Large enterprise deployments** with many teams, each having their own guardrails
|
||||
- **Multiple logging integrations** combined with custom callbacks
|
||||
- **Per-team callback configurations** that add up across your organization
|
||||
|
||||
## How to Override
|
||||
|
||||
Set the `LITELLM_MAX_CALLBACKS` environment variable to increase the limit:
|
||||
|
||||
```bash
|
||||
# Docker
|
||||
docker run -e LITELLM_MAX_CALLBACKS=100 ...
|
||||
|
||||
# Docker Compose
|
||||
environment:
|
||||
- LITELLM_MAX_CALLBACKS=100
|
||||
|
||||
# Kubernetes
|
||||
env:
|
||||
- name: LITELLM_MAX_CALLBACKS
|
||||
value: "100"
|
||||
|
||||
# Direct
|
||||
export LITELLM_MAX_CALLBACKS=100
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
## Recommendations
|
||||
|
||||
1. **Start conservative** - Only increase as much as you need. If you have 60 teams with guardrails, try `LITELLM_MAX_CALLBACKS=75` to leave headroom.
|
||||
|
||||
2. **Monitor performance** - More callbacks means more processing per request. Watch your CPU usage and response latency after increasing the limit.
|
||||
|
||||
3. **Consolidate where possible** - If multiple teams use identical guardrails, consider using shared callback configurations rather than per-team duplicates.
|
||||
|
||||
## Example: Large Enterprise Setup
|
||||
|
||||
For an organization with 60+ teams, each with a guardrail callback:
|
||||
|
||||
```yaml
|
||||
# config.yaml
|
||||
litellm_settings:
|
||||
callbacks: ["prometheus", "langfuse"] # 2 global callbacks
|
||||
|
||||
# Each team adds 1 guardrail callback = 60+ callbacks
|
||||
# Total: 62+ callbacks needed
|
||||
```
|
||||
|
||||
Set the environment variable:
|
||||
|
||||
```bash
|
||||
export LITELLM_MAX_CALLBACKS=100
|
||||
```
|
||||
49
docs/my-website/docs/troubleshoot/ui_issues.md
Normal file
|
|
@ -0,0 +1,49 @@
|
|||
# UI Troubleshooting
|
||||
|
||||
If you're experiencing issues with the LiteLLM Admin UI, please include the following information when reporting.
|
||||
|
||||
## 1. Steps to Reproduce
|
||||
|
||||
A clear, step-by-step description of how to trigger the issue (e.g., "Navigate to Settings → Team, click 'Create Team', fill in fields, click submit → error appears").
|
||||
|
||||
## 2. LiteLLM Version
|
||||
|
||||
The current version of LiteLLM you're running. Check via `litellm --version` or the UI's settings page.
|
||||
|
||||
## 3. Architecture & Deployment Setup
|
||||
|
||||
Distributed environments are a known source of UI issues. Please describe:
|
||||
|
||||
- **Number of LiteLLM instances/replicas** and how they are deployed (e.g., Kubernetes, Docker Compose, ECS)
|
||||
- **Load balancer** type and configuration (e.g., ALB, Nginx, Cloudflare Tunnel) — include whether sticky sessions are enabled
|
||||
- **How the UI is accessed** — directly via LiteLLM, through a reverse proxy, or behind an ingress controller
|
||||
- **Any CDN or caching layers** between the user and the LiteLLM server
|
||||
|
||||
## 4. Network Tab Requests
|
||||
|
||||
Open your browser's Developer Tools (F12 → Network tab), reproduce the issue, and share:
|
||||
|
||||
- The **failing request(s)** — URL, method, status code, and response body
|
||||
- **Screenshots or HAR export** of the relevant network activity
|
||||
- Any **CORS or mixed-content errors** shown in the Console tab
|
||||
|
||||
## 5. Environment Variables
|
||||
|
||||
Non-sensitive environment variables related to the UI and proxy setup, such as:
|
||||
|
||||
- `LITELLM_MASTER_KEY`
|
||||
- `PROXY_BASE_URL` / `LITELLM_PROXY_BASE_URL`
|
||||
- `UI_BASE_PATH`
|
||||
- Any SSO-related variables (e.g., `GOOGLE_CLIENT_ID`, `MICROSOFT_TENANT`)
|
||||
|
||||
Do **not** include passwords, secrets, or API keys.
|
||||
|
||||
## 6. Browser & Access Details
|
||||
|
||||
- **Browser** and version (e.g., Chrome 120, Firefox 121)
|
||||
- **Access URL** used to reach the UI (redact sensitive parts)
|
||||
- Whether the issue occurs for **all users or specific roles** (Admin, Internal User, etc.)
|
||||
|
||||
## 7. Screenshots or Screen Recordings
|
||||
|
||||
A screenshot or short screen recording of the issue is extremely helpful. Include any visible error messages, toasts, or unexpected behavior.
|
||||
279
docs/my-website/docs/tutorials/claude_code_beta_headers.md
Normal file
|
|
@ -0,0 +1,279 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Claude Code - Managing Anthropic Beta Headers
|
||||
|
||||
When using Claude Code with LiteLLM and non-Anthropic providers (Bedrock, Azure AI, Vertex AI), you need to ensure that only supported beta headers are sent to each provider. This guide explains how to add support for new beta headers or fix invalid beta header errors.
|
||||
|
||||
## What Are Beta Headers?
|
||||
|
||||
Anthropic uses beta headers to enable experimental features in Claude. When you use Claude Code, it may send beta headers like:
|
||||
|
||||
```
|
||||
anthropic-beta: prompt-caching-scope-2026-01-05,advanced-tool-use-2025-11-20
|
||||
```
|
||||
|
||||
However, not all providers support all Anthropic beta features. LiteLLM uses `anthropic_beta_headers_config.json` to manage which beta headers are supported by each provider.
|
||||
|
||||
## Common Error Message
|
||||
|
||||
```bash
|
||||
Error: The model returned the following errors: invalid beta flag
|
||||
```
|
||||
|
||||
## How LiteLLM Handles Beta Headers
|
||||
|
||||
LiteLLM uses a strict validation approach with a configuration file:
|
||||
|
||||
```
|
||||
litellm/litellm/anthropic_beta_headers_config.json
|
||||
```
|
||||
|
||||
This JSON file contains a **mapping** of beta headers for each provider:
|
||||
- **Keys**: Input beta header names (from Anthropic)
|
||||
- **Values**: Provider-specific header names (or `null` if unsupported)
|
||||
- **Validation**: Only headers present in the mapping with non-null values are forwarded
|
||||
|
||||
This enforces stricter validation than just filtering unsupported headers - headers must be explicitly defined to be allowed.
|
||||
|
||||
## Adding Support for a New Beta Header
|
||||
|
||||
When Anthropic releases a new beta feature, you need to add it to the configuration file for each provider.
|
||||
|
||||
### Step 1: Locate the Config File
|
||||
|
||||
Find the file in your LiteLLM installation:
|
||||
|
||||
```bash
|
||||
# If installed via pip
|
||||
cd $(python -c "import litellm; import os; print(os.path.dirname(litellm.__file__))")
|
||||
|
||||
# The config file is at:
|
||||
# litellm/anthropic_beta_headers_config.json
|
||||
```
|
||||
|
||||
### Step 2: Add the New Beta Header
|
||||
|
||||
Open `anthropic_beta_headers_config.json` and add the new header to each provider's mapping:
|
||||
|
||||
```json title="anthropic_beta_headers_config.json"
|
||||
{
|
||||
"description": "Mapping of Anthropic beta headers for each provider. Keys are input header names, values are provider-specific header names (or null if unsupported). Only headers present in mapping keys with non-null values can be forwarded.",
|
||||
"anthropic": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"new-feature-2026-03-01": "new-feature-2026-03-01",
|
||||
...
|
||||
},
|
||||
"azure_ai": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"new-feature-2026-03-01": "new-feature-2026-03-01",
|
||||
...
|
||||
},
|
||||
"bedrock_converse": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"new-feature-2026-03-01": null,
|
||||
...
|
||||
},
|
||||
"bedrock": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"new-feature-2026-03-01": null,
|
||||
...
|
||||
},
|
||||
"vertex_ai": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"new-feature-2026-03-01": null,
|
||||
...
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Key Points:**
|
||||
- **Supported headers**: Set the value to the provider-specific header name (often the same as the key)
|
||||
- **Unsupported headers**: Set the value to `null`
|
||||
- **Header transformations**: Some providers use different header names (e.g., Bedrock maps `advanced-tool-use-2025-11-20` to `tool-search-tool-2025-10-19`)
|
||||
- **Alphabetical order**: Keep headers sorted alphabetically for maintainability
|
||||
|
||||
### Step 3: Reload Configuration (No Restart Required!)
|
||||
|
||||
**Option 1: Dynamic Reload Without Restart**
|
||||
|
||||
Instead of restarting your application, you can dynamically reload the beta headers configuration using environment variables and API endpoints:
|
||||
|
||||
```bash
|
||||
# Set environment variable to fetch from remote URL (Do this if you want to point it to some other URL)
|
||||
export LITELLM_ANTHROPIC_BETA_HEADERS_URL="https://raw.githubusercontent.com/BerriAI/litellm/main/litellm/anthropic_beta_headers_config.json"
|
||||
|
||||
# Manually trigger reload via API (no restart needed!)
|
||||
curl -X POST "https://your-proxy-url/reload/anthropic_beta_headers" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
**Option 2: Schedule Automatic Reloads**
|
||||
|
||||
Set up automatic reloading to always stay up-to-date with the latest beta headers:
|
||||
|
||||
```bash
|
||||
# Reload configuration every 24 hours
|
||||
curl -X POST "https://your-proxy-url/schedule/anthropic_beta_headers_reload?hours=24" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
**Option 3: Traditional Restart**
|
||||
|
||||
If you prefer the traditional approach, restart your LiteLLM proxy or application:
|
||||
|
||||
```bash
|
||||
# If using LiteLLM proxy
|
||||
litellm --config config.yaml
|
||||
|
||||
# If using Python SDK
|
||||
# Just restart your Python application
|
||||
```
|
||||
|
||||
:::tip Zero-Downtime Updates
|
||||
With dynamic reloading, you can fix invalid beta header errors **without restarting your service**! This is especially useful in production environments where downtime is costly.
|
||||
|
||||
See [Auto Sync Anthropic Beta Headers](../proxy/sync_anthropic_beta_headers.md) for complete documentation.
|
||||
:::
|
||||
|
||||
## Fixing Invalid Beta Header Errors
|
||||
|
||||
If you encounter an "invalid beta flag" error, it means a beta header is being sent that the provider doesn't support.
|
||||
|
||||
### Step 1: Identify the Problematic Header
|
||||
|
||||
Check your logs to see which header is causing the issue:
|
||||
|
||||
```bash
|
||||
Error: The model returned the following errors: invalid beta flag: new-feature-2026-03-01
|
||||
```
|
||||
|
||||
### Step 2: Update the Config
|
||||
|
||||
Set the header value to `null` for that provider:
|
||||
|
||||
```json title="anthropic_beta_headers_config.json"
|
||||
{
|
||||
"bedrock_converse": {
|
||||
"new-feature-2026-03-01": null
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Step 3: Restart and Test
|
||||
|
||||
Restart your application and verify the header is now filtered out.
|
||||
|
||||
## Contributing a Fix to LiteLLM
|
||||
|
||||
Help the community by contributing your fix!
|
||||
|
||||
### What to Include in Your PR
|
||||
|
||||
1. **Update the config file**: Add the new beta header to `litellm/anthropic_beta_headers_config.json`
|
||||
2. **Test your changes**: Verify the header is correctly filtered/mapped for each provider
|
||||
3. **Documentation**: Include provider documentation links showing which headers are supported
|
||||
|
||||
### Example PR Description
|
||||
|
||||
```markdown
|
||||
## Add support for new-feature-2026-03-01 beta header
|
||||
|
||||
### Changes
|
||||
- Added `new-feature-2026-03-01` to anthropic_beta_headers_config.json
|
||||
- Set to `null` for bedrock_converse (unsupported)
|
||||
- Set to header name for anthropic, azure_ai (supported)
|
||||
|
||||
### Testing
|
||||
Tested with:
|
||||
- ✅ Anthropic: Header passed through correctly
|
||||
- ✅ Azure AI: Header passed through correctly
|
||||
- ✅ Bedrock Converse: Header filtered out (returns error without fix)
|
||||
|
||||
### References
|
||||
- Anthropic docs: [link]
|
||||
- AWS Bedrock docs: [link]
|
||||
```
|
||||
|
||||
|
||||
## How Beta Header Filtering Works
|
||||
|
||||
When you make a request through LiteLLM:
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant CC as Claude Code
|
||||
participant LP as LiteLLM
|
||||
participant Config as Beta Headers Config
|
||||
participant Provider as Provider (Bedrock/Azure/etc)
|
||||
|
||||
CC->>LP: Request with beta headers
|
||||
Note over CC,LP: anthropic-beta: header1,header2,header3
|
||||
|
||||
LP->>Config: Load header mapping for provider
|
||||
Config-->>LP: Returns mapping (header→value or null)
|
||||
|
||||
Note over LP: Validate & Transform:<br/>1. Check if header exists in mapping<br/>2. Filter out null values<br/>3. Map to provider-specific names
|
||||
|
||||
LP->>Provider: Request with filtered & mapped headers
|
||||
Note over LP,Provider: anthropic-beta: mapped-header2<br/>(header1, header3 filtered out)
|
||||
|
||||
Provider-->>LP: Success response
|
||||
LP-->>CC: Response
|
||||
```
|
||||
|
||||
### Filtering Rules
|
||||
|
||||
1. **Header must exist in mapping**: Unknown headers are filtered out
|
||||
2. **Header must have non-null value**: Headers with `null` values are filtered out
|
||||
3. **Header transformation**: Headers are mapped to provider-specific names (e.g., `advanced-tool-use-2025-11-20` → `tool-search-tool-2025-10-19` for Bedrock)
|
||||
|
||||
### Example
|
||||
|
||||
Request with headers:
|
||||
```
|
||||
anthropic-beta: advanced-tool-use-2025-11-20,computer-use-2025-01-24,unknown-header
|
||||
```
|
||||
|
||||
For Bedrock Converse:
|
||||
- ✅ `computer-use-2025-01-24` → `computer-use-2025-01-24` (supported, passed through)
|
||||
- ❌ `advanced-tool-use-2025-11-20` → filtered out (null value in config)
|
||||
- ❌ `unknown-header` → filtered out (not in config)
|
||||
|
||||
Result sent to Bedrock:
|
||||
```
|
||||
anthropic-beta: computer-use-2025-01-24
|
||||
```
|
||||
|
||||
## Dynamic Configuration Management (No Restart Required!)
|
||||
|
||||
### Environment Variables
|
||||
|
||||
Control how LiteLLM loads the beta headers configuration:
|
||||
|
||||
| Variable | Description | Default |
|
||||
|----------|-------------|---------|
|
||||
| `LITELLM_ANTHROPIC_BETA_HEADERS_URL` | URL to fetch config from | GitHub main branch |
|
||||
| `LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS` | Set to `True` to use local config only | `False` |
|
||||
|
||||
**Example: Use Custom Config URL**
|
||||
```bash
|
||||
export LITELLM_ANTHROPIC_BETA_HEADERS_URL="https://your-company.com/custom-beta-headers.json"
|
||||
```
|
||||
|
||||
**Example: Use Local Config Only (No Remote Fetching)**
|
||||
```bash
|
||||
export LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS=True
|
||||
```
|
||||
## Provider-Specific Notes
|
||||
|
||||
### Bedrock
|
||||
- Beta headers appear in both HTTP headers AND request body (`additionalModelRequestFields.anthropic_beta`)
|
||||
- Some headers are transformed (e.g., `advanced-tool-use` → `tool-search-tool`)
|
||||
|
||||
### Azure AI
|
||||
- Uses same header names as Anthropic
|
||||
- Some features not yet supported (check config for null values)
|
||||
|
||||
### Vertex AI
|
||||
- Some headers are transformed to match Vertex AI's implementation
|
||||
- Limited beta feature support compared to Anthropic
|
||||
|
|
@ -0,0 +1,43 @@
|
|||
# Claude Code - Prompt Cache Routing
|
||||
|
||||
Claude's [Prompt Caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching) feature helps to optimize API usage through attempting to cache prompts and re-use cached prompts during subsequent API calls. This feature is used by Claude Code.
|
||||
|
||||
When LiteLLM [load balancing](../proxy/load_balancing.md) is enabled, to ensure this prompt caching feature still works with Claude Code, LiteLLM needs to be configured to use the `PromptCachingDeploymentCheck` pre-call check. This pre-call check will ensure that API calls that used prompt caching are remembered and that subsequent API calls that try to use that prompt caching are routed to the same model deployment where a cache write occurred.
|
||||
|
||||
## Set Up
|
||||
|
||||
1. Configure the router so that it uses the `PromptCachingDeploymentCheck` (via setting the `optional_pre_call_checks` property), and configure the models so that they can access multiple deployments of Claude; below, we show an example for multiple AWS accounts (referred to as `account-1` and `account-2`, using the `aws_profile_name` property):
|
||||
```yaml
|
||||
router_settings:
|
||||
optional_pre_call_checks: ["prompt_caching"]
|
||||
|
||||
model_list:
|
||||
- litellm_params:
|
||||
model: us.anthropic.claude-sonnet-4-5-20250929-v1:0
|
||||
aws_profile_name: account-1
|
||||
aws_region_name: us-west-2
|
||||
model_info:
|
||||
litellm_provider: bedrock
|
||||
model_name: us.anthropic.claude-sonnet-4-5-20250929-v1:0
|
||||
- litellm_params:
|
||||
model: us.anthropic.claude-sonnet-4-5-20250929-v1:0
|
||||
aws_profile_name: account-2
|
||||
aws_region_name: us-west-2
|
||||
model_info:
|
||||
litellm_provider: bedrock
|
||||
model_name: us.anthropic.claude-sonnet-4-5-20250929-v1:0
|
||||
```
|
||||
2. Utilize Claude Code:
|
||||
1. Launch Claude Code, which will do a warm-up API call that tries to cache its warm-up prompt and its system prompt.
|
||||
2. Wait a few seconds, then quit Claude Code and re-open it.
|
||||
3. You'll notice that the warm-up API call successfully gets a cache hit (if using Claude Code in an IDE like VS Code, ensure that you don't do anything between step 2.1 and 2.2 here, otherwise there may not be a cache hit):
|
||||
1. Go to the [LiteLLM Request Logs page](../proxy/ui_logs.md) in the Admin UI
|
||||
2. Click on the individual requests to see (a) the cache creation and cache read tokens; and (b) the Model ID. In particular, the API call from step 2.1 should show a cache write, and the API call from step 2.2 should show a cache read; in addition, the Model ID should be equal (meaning the API call is getting forwarded to the same AWS account).
|
||||
|
||||
## Related
|
||||
|
||||
- [Claude Code - Quickstart](./claude_responses_api.md)
|
||||
- [Claude Code - Customer Tracking](./claude_code_customer_tracking.md)
|
||||
- [Claude Code - Plugin Marketplace](./claude_code_plugin_marketplace.md)
|
||||
- [Claude Code - WebSearch](./claude_code_websearch.md)
|
||||
- [Proxy - Load Balancing](../proxy/load_balancing.md)
|
||||
|
|
@ -9,7 +9,7 @@ Note: LiteLLM supports OAuth for MCP servers as well. [Learn more](https://docs.
|
|||
|
||||
## Connecting MCP Servers
|
||||
|
||||
You can also connect MCP servers to Claude Code via LiteLLM Proxy.
|
||||
You can connect MCP servers to Claude Code via LiteLLM Proxy.
|
||||
|
||||
|
||||
1. Add the MCP server to your `config.yaml`
|
||||
|
|
@ -23,6 +23,7 @@ In this example, we'll add the Github MCP server to our `config.yaml`
|
|||
mcp_servers:
|
||||
github_mcp:
|
||||
url: "https://api.githubcopilot.com/mcp"
|
||||
transport: "http"
|
||||
auth_type: oauth2
|
||||
client_id: os.environ/GITHUB_OAUTH_CLIENT_ID
|
||||
client_secret: os.environ/GITHUB_OAUTH_CLIENT_SECRET
|
||||
|
|
@ -34,31 +35,70 @@ mcp_servers:
|
|||
In this example, we'll add the Atlassian MCP server to our `config.yaml`
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
atlassian_mcp:
|
||||
server_id: atlassian_mcp_id
|
||||
url: "https://mcp.atlassian.com/v1/sse"
|
||||
transport: "sse"
|
||||
auth_type: oauth2
|
||||
mcp_servers:
|
||||
atlassian_mcp:
|
||||
url: "https://mcp.atlassian.com/v1/mcp"
|
||||
transport: "http"
|
||||
auth_type: oauth2
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
:::important
|
||||
The server name under `mcp_servers:` (e.g. `atlassian_mcp`, `github_mcp`) **must match** the name used in the Claude Code URL path (`/mcp/<server_name>`). A mismatch will cause a 404 error during OAuth.
|
||||
:::
|
||||
|
||||
2. Start LiteLLM Proxy
|
||||
|
||||
Since Claude Code needs a publicly accessible URL for the OAuth callback, expose your proxy via ngrok or a similar tool.
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
3. Use the MCP server in Claude Code
|
||||
|
||||
```bash
|
||||
claude mcp add --transport http litellm_proxy http://0.0.0.0:4000/github_mcp/mcp --header "Authorization: Bearer sk-LITELLM_VIRTUAL_KEY"
|
||||
# In a separate terminal — expose proxy for OAuth callbacks
|
||||
ngrok http 4000
|
||||
```
|
||||
|
||||
For MCP servers that require dynamic client registration (such as Atlassian), please set `x-litellm-api-key: Bearer sk-LITELLM_VIRTUAL_KEY` instead of using `Authorization: Bearer LITELLM_VIRTUAL_KEY`.
|
||||
3. Add the MCP server to Claude Code
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="github" label="GitHub MCP">
|
||||
|
||||
```bash
|
||||
claude mcp add --transport http litellm-github https://your-ngrok-url.ngrok-free.dev/mcp/github_mcp \
|
||||
--header "x-litellm-api-key: Bearer sk-1234"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="atlassian" label="Atlassian MCP">
|
||||
|
||||
```bash
|
||||
claude mcp add --transport http litellm-atlassian https://your-ngrok-url.ngrok-free.dev/mcp/atlassian_mcp \
|
||||
--header "x-litellm-api-key: Bearer sk-1234"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
**Parameter breakdown:**
|
||||
|
||||
| Parameter | Description |
|
||||
|-----------|-------------|
|
||||
| `--transport http` | Use HTTP transport for the MCP connection |
|
||||
| `litellm-atlassian` | The name for this MCP server **on Claude Code** — can be anything you choose |
|
||||
| `https://your-ngrok-url.ngrok-free.dev/mcp/atlassian_mcp` | The LiteLLM proxy URL. Format: `<PROXY_URL>/mcp/<server_name_on_litellm>`. The `atlassian_mcp` part **must match** the key under `mcp_servers:` in your LiteLLM proxy config |
|
||||
| `--header "x-litellm-api-key: Bearer sk-1234"` | Your LiteLLM virtual key for authentication to the proxy |
|
||||
|
||||
You can also add the MCP server directly to your `~/.claude.json` file instead of using `claude mcp add`. [See Claude Code docs](https://docs.anthropic.com/en/docs/claude-code/mcp).
|
||||
|
||||
:::note
|
||||
For MCP servers that require OAuth (such as Atlassian), use `x-litellm-api-key` instead of `Authorization` for the LiteLLM virtual key. The `Authorization` header is reserved for the OAuth flow.
|
||||
:::
|
||||
|
||||
4. Authenticate via Claude Code
|
||||
|
||||
|
|
@ -68,24 +108,20 @@ a. Start Claude Code
|
|||
claude
|
||||
```
|
||||
|
||||
b. Authenticate via Claude Code
|
||||
b. Open the MCP menu
|
||||
|
||||
```bash
|
||||
/mcp
|
||||
```
|
||||
|
||||
c. Select the MCP server
|
||||
c. Select the MCP server (e.g. `litellm-atlassian`)
|
||||
|
||||
```bash
|
||||
> litellm_proxy
|
||||
```
|
||||
|
||||
d. Start Oauth flow via Claude Code
|
||||
d. Start the OAuth flow
|
||||
|
||||
```bash
|
||||
> 1. Authenticate
|
||||
2. Reconnect
|
||||
3. Disable
|
||||
3. Disable
|
||||
```
|
||||
|
||||
e. Once completed, you should see this success message:
|
||||
|
|
|
|||
99
docs/my-website/docs/tutorials/copilotkit_sdk.md
Normal file
|
|
@ -0,0 +1,99 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# CopilotKit SDK with LiteLLM
|
||||
|
||||
Use CopilotKit SDK with any LLM provider through LiteLLM Proxy.
|
||||
|
||||
> **Note:** CopilotKit SDK integration with LiteLLM Proxy works with LiteLLM v1.81.7-nightly or higher.
|
||||
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Add Model to Config
|
||||
|
||||
```yaml title="config.yaml"
|
||||
model_list:
|
||||
- model_name: claude-sonnet-4-5
|
||||
litellm_params:
|
||||
model: "anthropic/claude-sonnet-4-5-20250514-v1:0"
|
||||
api_key: "os.environ/ANTHROPIC_API_KEY"
|
||||
```
|
||||
|
||||
### 2. Start LiteLLM Proxy
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
### 3. Use CopilotKit SDK
|
||||
|
||||
```typescript
|
||||
import OpenAI from "openai";
|
||||
import {
|
||||
CopilotRuntime,
|
||||
OpenAIAdapter,
|
||||
copilotRuntimeNextJSAppRouterEndpoint,
|
||||
} from "@copilotkit/runtime";
|
||||
import { NextRequest } from "next/server";
|
||||
|
||||
const model = "claude-sonnet-4-5";
|
||||
|
||||
const openai = new OpenAI({
|
||||
apiKey: process.env.OPENAI_API_KEY || "sk-12345",
|
||||
baseURL: process.env.OPENAI_BASE_URL || "http://localhost:4000/v1",
|
||||
});
|
||||
|
||||
const serviceAdapter = new OpenAIAdapter({ openai, model });
|
||||
const runtime = new CopilotRuntime();
|
||||
|
||||
export const POST = async (req: NextRequest) => {
|
||||
const { handleRequest } = copilotRuntimeNextJSAppRouterEndpoint({
|
||||
runtime,
|
||||
serviceAdapter,
|
||||
endpoint: "/api/copilotkit",
|
||||
});
|
||||
return handleRequest(req);
|
||||
};
|
||||
```
|
||||
|
||||
### 4. Test
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:3000/api/copilotkit \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"method": "agent/run",
|
||||
"params": {
|
||||
"agentId": "default"
|
||||
},
|
||||
"runId": "your_run_id",
|
||||
"threadId": "your_thread_id",
|
||||
"runId": ""your_run_id"",
|
||||
"tools": [],
|
||||
"context": [],
|
||||
"forwardedProps": {},
|
||||
"state": {},
|
||||
"messages": [
|
||||
{
|
||||
"id": "166e573e-f7c6-4c0f-8685-04dbefec18be",
|
||||
"content": "Hi",
|
||||
"role": "user"
|
||||
}
|
||||
]
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
## Environment Variables
|
||||
|
||||
| Variable | Value | Description |
|
||||
|----------|-------|-------------|
|
||||
| `OPENAI_API_KEY` | `sk-12345` | Your LiteLLM API key |
|
||||
| `OPENAI_BASE_URL` | `http://localhost:4000/v1` | LiteLLM proxy URL |
|
||||
|
||||
|
||||
## Related Resources
|
||||
|
||||
- [CopilotKit Documentation](https://docs.copilotkit.ai)
|
||||
- [LiteLLM Proxy Quick Start](../proxy/quick_start)
|
||||
190
docs/my-website/docs/tutorials/livekit_xai_realtime.md
Normal file
|
|
@ -0,0 +1,190 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# LiveKit xAI Realtime Voice Agent
|
||||
|
||||
Use LiveKit's xAI Grok Voice Agent plugin with LiteLLM Proxy to build low-latency voice AI agents.
|
||||
|
||||
The LiveKit Agents framework provides tools for building real-time voice and video AI applications. By routing through LiteLLM Proxy, you get unified access to multiple realtime voice providers, cost tracking, rate limiting, and more.
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Install Dependencies
|
||||
|
||||
```bash
|
||||
pip install livekit-agents[xai]
|
||||
```
|
||||
|
||||
### 2. Start LiteLLM Proxy
|
||||
|
||||
Create a config file with your xAI realtime model:
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
model_list:
|
||||
- model_name: grok-voice-agent
|
||||
litellm_params:
|
||||
model: xai/grok-2-vision-1212
|
||||
api_key: os.environ/XAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
|
||||
litellm_settings:
|
||||
drop_params: True
|
||||
|
||||
general_settings:
|
||||
master_key: sk-1234 # Change this to a secure key
|
||||
```
|
||||
|
||||
Start the proxy:
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml --port 4000
|
||||
```
|
||||
|
||||
### 3. Configure LiveKit xAI Plugin
|
||||
|
||||
Point LiveKit's xAI plugin to your LiteLLM proxy:
|
||||
|
||||
```python
|
||||
from livekit.plugins import xai
|
||||
|
||||
# Configure xAI to use LiteLLM proxy
|
||||
model = xai.realtime.RealtimeModel(
|
||||
voice="ara", # Voice option
|
||||
api_key="sk-1234", # Your LiteLLM proxy master key
|
||||
base_url="http://localhost:4000", # LiteLLM proxy URL
|
||||
)
|
||||
```
|
||||
|
||||
## Complete Example
|
||||
|
||||
Here's a complete working example:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="python" label="Python Client">
|
||||
|
||||
```python
|
||||
#!/usr/bin/env python3
|
||||
"""
|
||||
Simple xAI realtime voice agent through LiteLLM proxy.
|
||||
"""
|
||||
import asyncio
|
||||
import json
|
||||
import websockets
|
||||
|
||||
PROXY_URL = "ws://localhost:4000/v1/realtime"
|
||||
API_KEY = "sk-1234"
|
||||
MODEL = "grok-voice-agent"
|
||||
|
||||
async def run_voice_agent():
|
||||
"""Connect to xAI realtime API through LiteLLM proxy"""
|
||||
url = f"{PROXY_URL}?model={MODEL}"
|
||||
headers = {"Authorization": f"Bearer {API_KEY}"}
|
||||
|
||||
async with websockets.connect(url, extra_headers=headers) as ws:
|
||||
# Wait for initial connection event
|
||||
initial = json.loads(await ws.recv())
|
||||
print(f"✅ Connected: {initial['type']}")
|
||||
|
||||
# Send user message
|
||||
await ws.send(json.dumps({
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{
|
||||
"type": "input_text",
|
||||
"text": "Hello! Tell me a joke."
|
||||
}]
|
||||
}
|
||||
}))
|
||||
|
||||
# Request response
|
||||
await ws.send(json.dumps({
|
||||
"type": "response.create",
|
||||
"response": {"modalities": ["text", "audio"]}
|
||||
}))
|
||||
|
||||
# Collect response
|
||||
transcript = []
|
||||
async for message in ws:
|
||||
event = json.loads(message)
|
||||
|
||||
# Capture text response
|
||||
if event['type'] == 'response.output_audio_transcript.delta':
|
||||
transcript.append(event['delta'])
|
||||
print(event['delta'], end='', flush=True)
|
||||
|
||||
# Done when response completes
|
||||
elif event['type'] == 'response.done':
|
||||
break
|
||||
|
||||
print(f"\n\n✅ Full response: {''.join(transcript)}")
|
||||
|
||||
if __name__ == "__main__":
|
||||
asyncio.run(run_voice_agent())
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="livekit" label="LiveKit Agent">
|
||||
|
||||
```python
|
||||
from livekit.agents import Agent, AgentSession, WorkerOptions, cli
|
||||
from livekit.plugins import xai
|
||||
|
||||
class VoiceAgent(Agent):
|
||||
def __init__(self):
|
||||
super().__init__(
|
||||
instructions="You are a helpful voice assistant.",
|
||||
llm=xai.realtime.RealtimeModel(
|
||||
voice="ara",
|
||||
api_key="sk-1234",
|
||||
base_url="http://localhost:4000",
|
||||
),
|
||||
)
|
||||
|
||||
if __name__ == "__main__":
|
||||
cli.run_app(
|
||||
WorkerOptions(
|
||||
agent_factory=VoiceAgent,
|
||||
)
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Running the Example
|
||||
|
||||
1. **Start LiteLLM Proxy** (if not already running):
|
||||
```bash
|
||||
litellm --config config.yaml --port 4000
|
||||
```
|
||||
|
||||
2. **Run the example**:
|
||||
```bash
|
||||
python your_script.py
|
||||
```
|
||||
|
||||
## Expected Output
|
||||
|
||||
```
|
||||
✅ Connected: conversation.created
|
||||
Hello! Here's a joke for you: Why don't scientists trust atoms?
|
||||
Because they make up everything!
|
||||
|
||||
✅ Full response: Hello! Here's a joke for you: Why don't scientists trust atoms? Because they make up everything!
|
||||
```
|
||||
|
||||
|
||||
## Complete Working Example
|
||||
|
||||
**[LiveKit Agent SDK Cookbook](https://github.com/BerriAI/litellm/tree/main/cookbook/livekit_agent_sdk)**
|
||||
|
||||
|
||||
## Learn More
|
||||
|
||||
- [xAI Realtime API](/docs/providers/xai_realtime)
|
||||
- [LiveKit xAI Plugin](https://docs.livekit.io/agents/models/realtime/plugins/xai/)
|
||||
- [LiteLLM Realtime API](/docs/realtime)
|
||||
BIN
docs/my-website/img/okta_access_policies.png
Normal file

|
After Width: | Height: | Size: 82 KiB |
BIN
docs/my-website/img/okta_authorization_server.png
Normal file

|
After Width: | Height: | Size: 52 KiB |
BIN
docs/my-website/img/okta_client_credentials.png
Normal file

|
After Width: | Height: | Size: 64 KiB |
BIN
docs/my-website/img/okta_redirect_uri.png
Normal file

|
After Width: | Height: | Size: 60 KiB |
BIN
docs/my-website/img/okta_security_api.png
Normal file

|
After Width: | Height: | Size: 38 KiB |
BIN
docs/my-website/img/policy_team_attach.png
Normal file

|
After Width: | Height: | Size: 225 KiB |
BIN
docs/my-website/img/policy_test_matching.png
Normal file

|
After Width: | Height: | Size: 200 KiB |
BIN
docs/my-website/img/release_notes/guard_actions.png
Normal file

|
After Width: | Height: | Size: 506 KiB |
BIN
docs/my-website/img/release_notes/mcp_internet.png
Normal file

|
After Width: | Height: | Size: 724 KiB |
BIN
docs/my-website/img/ui_access_groups.png
Normal file

|
After Width: | Height: | Size: 338 KiB |
BIN
docs/my-website/img/ui_team_soft_budget_alerts.png
Normal file

|
After Width: | Height: | Size: 328 KiB |
BIN
docs/my-website/img/ui_team_soft_budget_email_example.png
Normal file

|
After Width: | Height: | Size: 50 KiB |
7
docs/my-website/package-lock.json
generated
|
|
@ -20455,6 +20455,13 @@
|
|||
"url": "https://opencollective.com/webpack"
|
||||
}
|
||||
},
|
||||
"node_modules/search-insights": {
|
||||
"version": "2.17.3",
|
||||
"resolved": "https://registry.npmjs.org/search-insights/-/search-insights-2.17.3.tgz",
|
||||
"integrity": "sha512-RQPdCYTa8A68uM2jwxoY842xDhvx3E5LFL1LxvxCNMev4o5mLuokczhzjAgGwUZBAmOKZknArSxLKmXtIi2AxQ==",
|
||||
"license": "MIT",
|
||||
"peer": true
|
||||
},
|
||||
"node_modules/section-matter": {
|
||||
"version": "1.0.0",
|
||||
"resolved": "https://registry.npmjs.org/section-matter/-/section-matter-1.0.0.tgz",
|
||||
|
|
|
|||
|
|
@ -61,6 +61,8 @@
|
|||
"mermaid": ">=11.10.0",
|
||||
"gray-matter": "4.0.3",
|
||||
"glob": ">=11.1.0",
|
||||
"tar": ">=7.5.7",
|
||||
"@isaacs/brace-expansion": ">=5.0.1",
|
||||
"node-forge": ">=1.3.2",
|
||||
"mdast-util-to-hast": ">=13.2.1",
|
||||
"lodash-es": ">=4.17.23"
|
||||
|
|
|
|||