mirror of
https://github.com/BerriAI/litellm.git
synced 2026-09-30 01:52:18 +00:00
Merge branch 'BerriAI:main' into main
This commit is contained in:
 Rena Lu
GitHub
commit
ae0ede4190
69 changed files with 1256 additions and 323 deletions
0
template.yaml → .github/template.yaml
vendored
0
template.yaml → .github/template.yaml
vendored
14
README.md
14
README.md
|
|
@ -5,7 +5,7 @@
|
|||
<p align="center">Call all LLM APIs using the OpenAI format [Bedrock, Huggingface, VertexAI, TogetherAI, Azure, OpenAI, etc.]
|
||||
<br>
|
||||
</p>
|
||||
<h4 align="center"><a href="https://docs.litellm.ai/docs/simple_proxy" target="_blank">OpenAI Proxy Server</a></h4>
|
||||
<h4 align="center"><a href="https://docs.litellm.ai/docs/simple_proxy" target="_blank">OpenAI Proxy Server</a> | <a href="https://docs.litellm.ai/docs/enterprise"target="_blank">Enterprise Support</a></h4>
|
||||
<h4 align="center">
|
||||
<a href="https://pypi.org/project/litellm/" target="_blank">
|
||||
<img src="https://img.shields.io/pypi/v/litellm.svg" alt="PyPI Version">
|
||||
|
|
@ -28,6 +28,8 @@ LiteLLM manages:
|
|||
- Translate inputs to provider's `completion`, `embedding`, and `image_generation` endpoints
|
||||
- [Consistent output](https://docs.litellm.ai/docs/completion/output), text responses will always be available at `['choices'][0]['message']['content']`
|
||||
- Retry/fallback logic across multiple deployments (e.g. Azure/OpenAI) - [Router](https://docs.litellm.ai/docs/routing)
|
||||
- Track spend & set budgets per project [OpenAI Proxy Server](https://docs.litellm.ai/docs/simple_proxy)
|
||||
|
||||
|
||||
[**Jump to OpenAI Proxy Docs**](https://github.com/BerriAI/litellm?tab=readme-ov-file#openai-proxy---docs) <br>
|
||||
[**Jump to Supported LLM Providers**](https://github.com/BerriAI/litellm?tab=readme-ov-file#supported-provider-docs)
|
||||
|
|
@ -155,6 +157,9 @@ print(response)
|
|||
```
|
||||
|
||||
## Proxy Key Management ([Docs](https://docs.litellm.ai/docs/proxy/virtual_keys))
|
||||
UI on `/ui` on your proxy server
|
||||
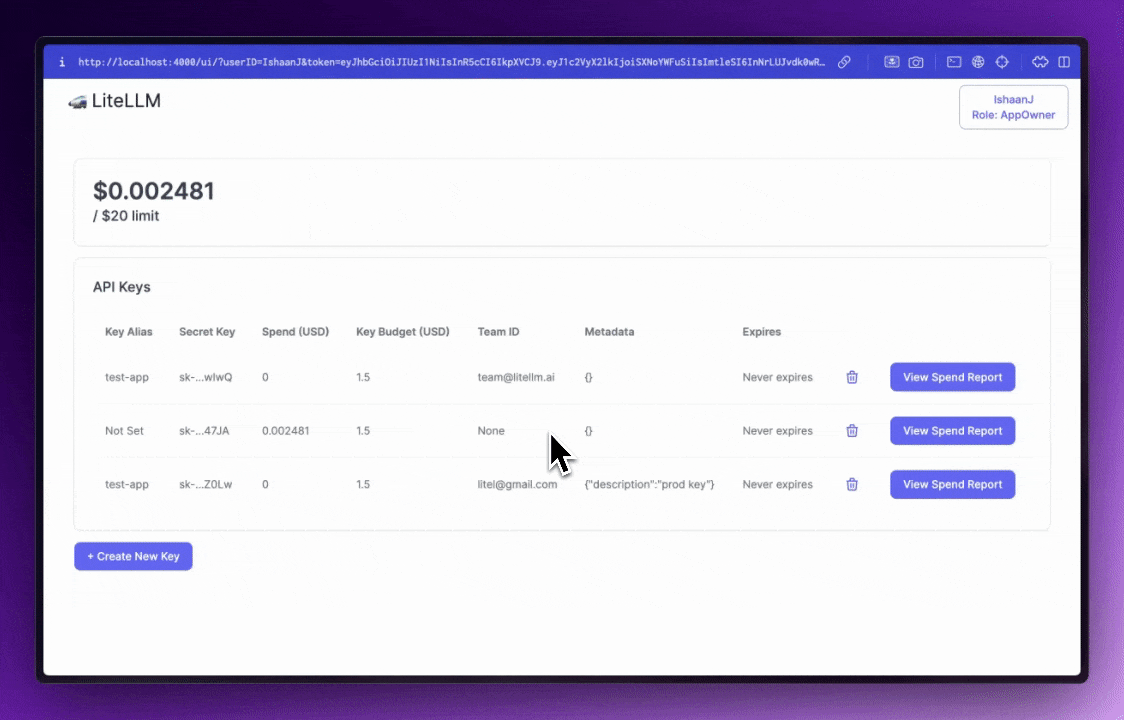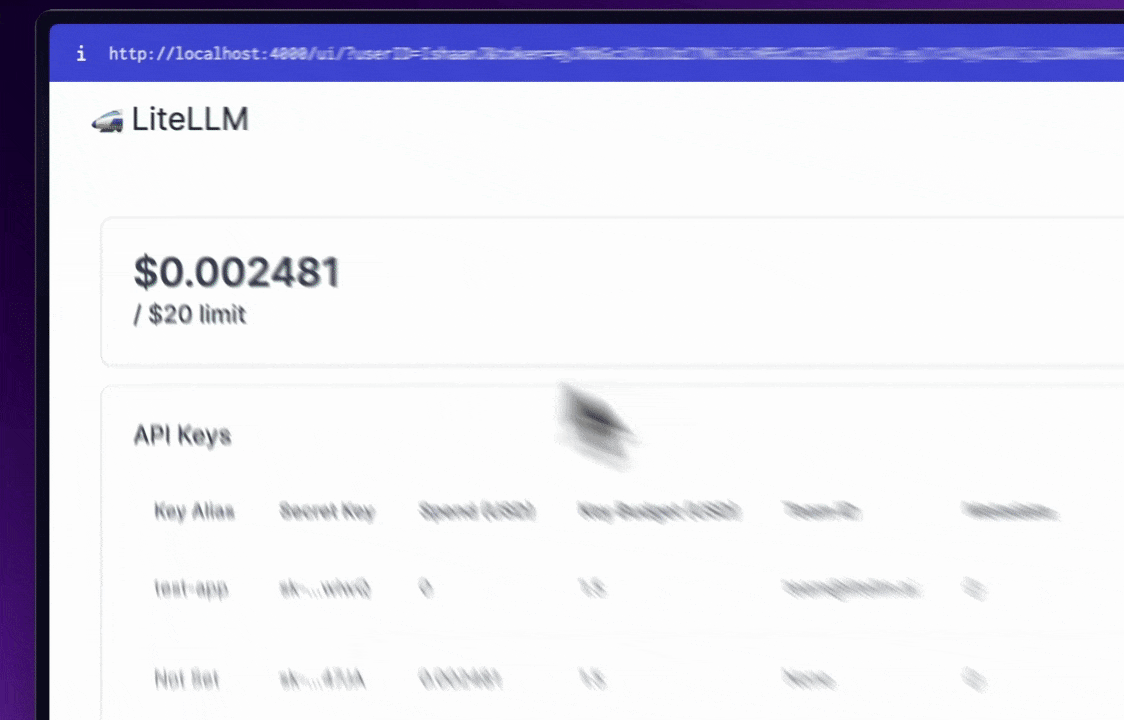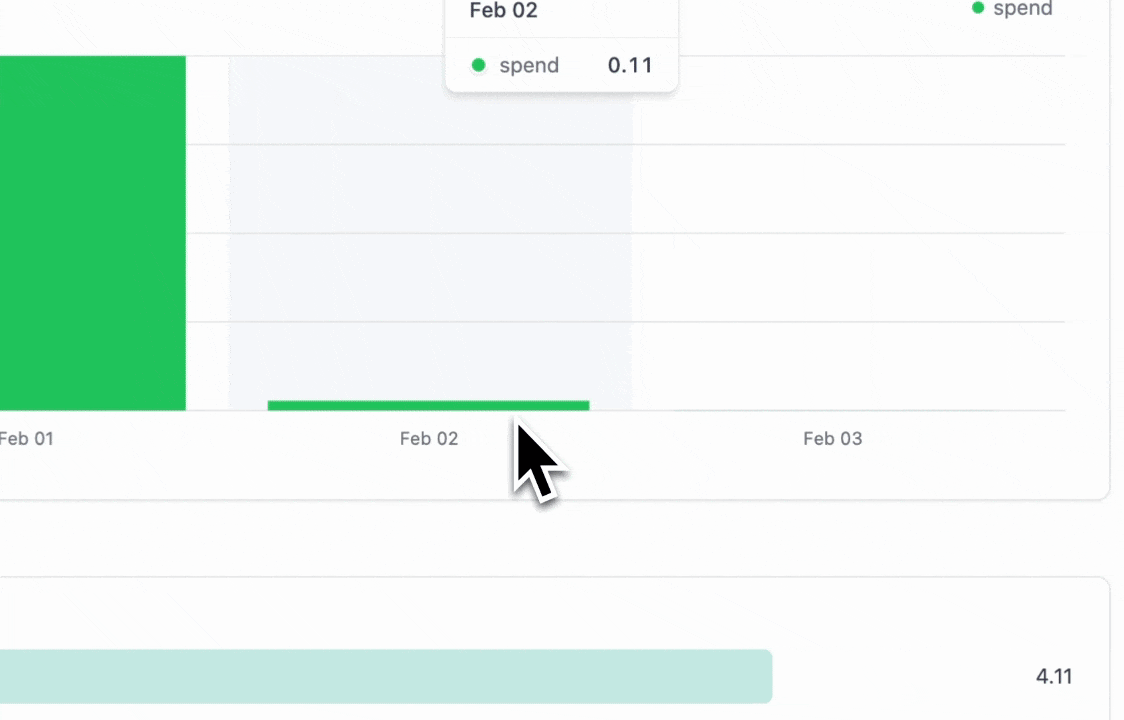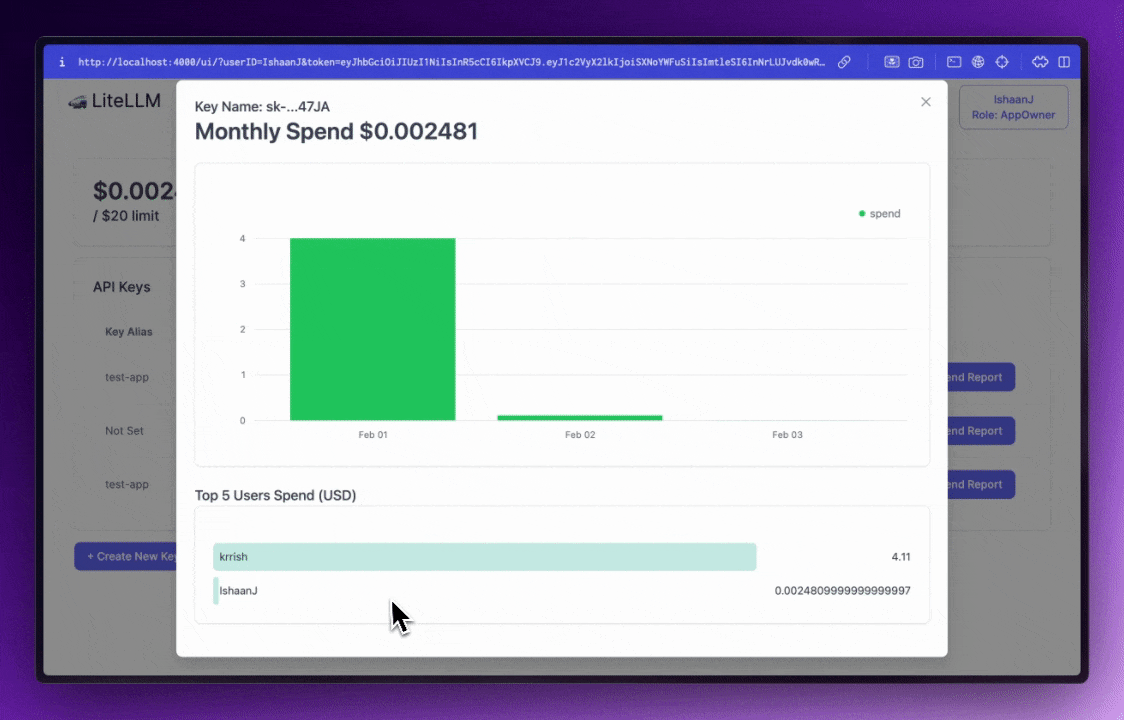
|
||||
|
||||
Track Spend, Set budgets and create virtual keys for the proxy
|
||||
`POST /key/generate`
|
||||
|
||||
|
|
@ -174,13 +179,6 @@ curl 'http://0.0.0.0:8000/key/generate' \
|
|||
}
|
||||
```
|
||||
|
||||
### [Beta] Proxy UI ([Docs](https://docs.litellm.ai/docs/proxy/ui))
|
||||
|
||||
A UI to create keys, track spend per key
|
||||
|
||||
Code: https://github.com/BerriAI/litellm/tree/main/ui
|
||||

|
||||
|
||||
## Supported Providers ([Docs](https://docs.litellm.ai/docs/providers))
|
||||
| Provider | [Completion](https://docs.litellm.ai/docs/#basic-usage) | [Streaming](https://docs.litellm.ai/docs/completion/stream#streaming-responses) | [Async Completion](https://docs.litellm.ai/docs/completion/stream#async-completion) | [Async Streaming](https://docs.litellm.ai/docs/completion/stream#async-streaming) | [Async Embedding](https://docs.litellm.ai/docs/embedding/supported_embedding) | [Async Image Generation](https://docs.litellm.ai/docs/image_generation) |
|
||||
| ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- |
|
||||
|
|
|
|||
|
|
@ -0,0 +1,76 @@
|
|||
import sys, os
|
||||
import traceback
|
||||
from dotenv import load_dotenv
|
||||
import copy
|
||||
|
||||
load_dotenv()
|
||||
sys.path.insert(
|
||||
0, os.path.abspath("../..")
|
||||
) # Adds the parent directory to the system path
|
||||
import asyncio
|
||||
from litellm import Router, Timeout
|
||||
import time
|
||||
from litellm.caching import Cache
|
||||
import litellm
|
||||
import openai
|
||||
|
||||
### Test just calling AsyncAzureOpenAI
|
||||
|
||||
openai_client = openai.AsyncAzureOpenAI(
|
||||
azure_endpoint=os.getenv("AZURE_API_BASE"),
|
||||
api_key=os.getenv("AZURE_API_KEY"),
|
||||
)
|
||||
|
||||
|
||||
async def call_acompletion(semaphore, input_data):
|
||||
async with semaphore:
|
||||
try:
|
||||
# Use asyncio.wait_for to set a timeout for the task
|
||||
response = await openai_client.chat.completions.create(**input_data)
|
||||
# Handle the response as needed
|
||||
print(response)
|
||||
return response
|
||||
except Timeout:
|
||||
print(f"Task timed out: {input_data}")
|
||||
return None # You may choose to return something else or raise an exception
|
||||
|
||||
|
||||
async def main():
|
||||
# Initialize the Router
|
||||
|
||||
# Create a semaphore with a capacity of 100
|
||||
semaphore = asyncio.Semaphore(100)
|
||||
|
||||
# List to hold all task references
|
||||
tasks = []
|
||||
start_time_all_tasks = time.time()
|
||||
# Launch 1000 tasks
|
||||
for _ in range(500):
|
||||
task = asyncio.create_task(
|
||||
call_acompletion(
|
||||
semaphore,
|
||||
{
|
||||
"model": "chatgpt-v-2",
|
||||
"messages": [{"role": "user", "content": "Hey, how's it going?"}],
|
||||
},
|
||||
)
|
||||
)
|
||||
tasks.append(task)
|
||||
|
||||
# Wait for all tasks to complete
|
||||
responses = await asyncio.gather(*tasks)
|
||||
# Process responses as needed
|
||||
# Record the end time for all tasks
|
||||
end_time_all_tasks = time.time()
|
||||
# Calculate the total time for all tasks
|
||||
total_time_all_tasks = end_time_all_tasks - start_time_all_tasks
|
||||
print(f"Total time for all tasks: {total_time_all_tasks} seconds")
|
||||
|
||||
# Calculate the average time per response
|
||||
average_time_per_response = total_time_all_tasks / len(responses)
|
||||
print(f"Average time per response: {average_time_per_response} seconds")
|
||||
print(f"NUMBER OF COMPLETED TASKS: {len(responses)}")
|
||||
|
||||
|
||||
# Run the main function
|
||||
asyncio.run(main())
|
||||
88
cookbook/litellm_router_load_test/test_loadtest_router.py
Normal file
88
cookbook/litellm_router_load_test/test_loadtest_router.py
Normal file
|
|
@ -0,0 +1,88 @@
|
|||
import sys, os
|
||||
import traceback
|
||||
from dotenv import load_dotenv
|
||||
import copy
|
||||
|
||||
load_dotenv()
|
||||
sys.path.insert(
|
||||
0, os.path.abspath("../..")
|
||||
) # Adds the parent directory to the system path
|
||||
import asyncio
|
||||
from litellm import Router, Timeout
|
||||
import time
|
||||
|
||||
### Test calling router async
|
||||
|
||||
|
||||
async def call_acompletion(semaphore, router: Router, input_data):
|
||||
async with semaphore:
|
||||
try:
|
||||
# Use asyncio.wait_for to set a timeout for the task
|
||||
response = await router.acompletion(**input_data)
|
||||
# Handle the response as needed
|
||||
print(response)
|
||||
return response
|
||||
except Timeout:
|
||||
print(f"Task timed out: {input_data}")
|
||||
return None # You may choose to return something else or raise an exception
|
||||
|
||||
|
||||
async def main():
|
||||
# Initialize the Router
|
||||
model_list = [
|
||||
{
|
||||
"model_name": "gpt-3.5-turbo",
|
||||
"litellm_params": {
|
||||
"model": "gpt-3.5-turbo",
|
||||
"api_key": os.getenv("OPENAI_API_KEY"),
|
||||
},
|
||||
},
|
||||
{
|
||||
"model_name": "gpt-3.5-turbo",
|
||||
"litellm_params": {
|
||||
"model": "azure/chatgpt-v-2",
|
||||
"api_key": os.getenv("AZURE_API_KEY"),
|
||||
"api_base": os.getenv("AZURE_API_BASE"),
|
||||
"api_version": os.getenv("AZURE_API_VERSION"),
|
||||
},
|
||||
},
|
||||
]
|
||||
router = Router(model_list=model_list, num_retries=3, timeout=10)
|
||||
|
||||
# Create a semaphore with a capacity of 100
|
||||
semaphore = asyncio.Semaphore(100)
|
||||
|
||||
# List to hold all task references
|
||||
tasks = []
|
||||
start_time_all_tasks = time.time()
|
||||
# Launch 1000 tasks
|
||||
for _ in range(500):
|
||||
task = asyncio.create_task(
|
||||
call_acompletion(
|
||||
semaphore,
|
||||
router,
|
||||
{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [{"role": "user", "content": "Hey, how's it going?"}],
|
||||
},
|
||||
)
|
||||
)
|
||||
tasks.append(task)
|
||||
|
||||
# Wait for all tasks to complete
|
||||
responses = await asyncio.gather(*tasks)
|
||||
# Process responses as needed
|
||||
# Record the end time for all tasks
|
||||
end_time_all_tasks = time.time()
|
||||
# Calculate the total time for all tasks
|
||||
total_time_all_tasks = end_time_all_tasks - start_time_all_tasks
|
||||
print(f"Total time for all tasks: {total_time_all_tasks} seconds")
|
||||
|
||||
# Calculate the average time per response
|
||||
average_time_per_response = total_time_all_tasks / len(responses)
|
||||
print(f"Average time per response: {average_time_per_response} seconds")
|
||||
print(f"NUMBER OF COMPLETED TASKS: {len(responses)}")
|
||||
|
||||
|
||||
# Run the main function
|
||||
asyncio.run(main())
|
||||
|
|
@ -0,0 +1,94 @@
|
|||
import sys, os
|
||||
import traceback
|
||||
from dotenv import load_dotenv
|
||||
import copy
|
||||
|
||||
load_dotenv()
|
||||
sys.path.insert(
|
||||
0, os.path.abspath("../..")
|
||||
) # Adds the parent directory to the system path
|
||||
import asyncio
|
||||
from litellm import Router, Timeout
|
||||
import time
|
||||
from litellm.caching import Cache
|
||||
import litellm
|
||||
|
||||
litellm.cache = Cache(
|
||||
type="s3", s3_bucket_name="cache-bucket-litellm", s3_region_name="us-west-2"
|
||||
)
|
||||
|
||||
### Test calling router with s3 Cache
|
||||
|
||||
|
||||
async def call_acompletion(semaphore, router: Router, input_data):
|
||||
async with semaphore:
|
||||
try:
|
||||
# Use asyncio.wait_for to set a timeout for the task
|
||||
response = await router.acompletion(**input_data)
|
||||
# Handle the response as needed
|
||||
print(response)
|
||||
return response
|
||||
except Timeout:
|
||||
print(f"Task timed out: {input_data}")
|
||||
return None # You may choose to return something else or raise an exception
|
||||
|
||||
|
||||
async def main():
|
||||
# Initialize the Router
|
||||
model_list = [
|
||||
{
|
||||
"model_name": "gpt-3.5-turbo",
|
||||
"litellm_params": {
|
||||
"model": "gpt-3.5-turbo",
|
||||
"api_key": os.getenv("OPENAI_API_KEY"),
|
||||
},
|
||||
},
|
||||
{
|
||||
"model_name": "gpt-3.5-turbo",
|
||||
"litellm_params": {
|
||||
"model": "azure/chatgpt-v-2",
|
||||
"api_key": os.getenv("AZURE_API_KEY"),
|
||||
"api_base": os.getenv("AZURE_API_BASE"),
|
||||
"api_version": os.getenv("AZURE_API_VERSION"),
|
||||
},
|
||||
},
|
||||
]
|
||||
router = Router(model_list=model_list, num_retries=3, timeout=10)
|
||||
|
||||
# Create a semaphore with a capacity of 100
|
||||
semaphore = asyncio.Semaphore(100)
|
||||
|
||||
# List to hold all task references
|
||||
tasks = []
|
||||
start_time_all_tasks = time.time()
|
||||
# Launch 1000 tasks
|
||||
for _ in range(500):
|
||||
task = asyncio.create_task(
|
||||
call_acompletion(
|
||||
semaphore,
|
||||
router,
|
||||
{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [{"role": "user", "content": "Hey, how's it going?"}],
|
||||
},
|
||||
)
|
||||
)
|
||||
tasks.append(task)
|
||||
|
||||
# Wait for all tasks to complete
|
||||
responses = await asyncio.gather(*tasks)
|
||||
# Process responses as needed
|
||||
# Record the end time for all tasks
|
||||
end_time_all_tasks = time.time()
|
||||
# Calculate the total time for all tasks
|
||||
total_time_all_tasks = end_time_all_tasks - start_time_all_tasks
|
||||
print(f"Total time for all tasks: {total_time_all_tasks} seconds")
|
||||
|
||||
# Calculate the average time per response
|
||||
average_time_per_response = total_time_all_tasks / len(responses)
|
||||
print(f"Average time per response: {average_time_per_response} seconds")
|
||||
print(f"NUMBER OF COMPLETED TASKS: {len(responses)}")
|
||||
|
||||
|
||||
# Run the main function
|
||||
asyncio.run(main())
|
||||
15
docs/my-website/docs/enterprise.md
Normal file
15
docs/my-website/docs/enterprise.md
Normal file
|
|
@ -0,0 +1,15 @@
|
|||
# Enterprise
|
||||
|
||||
LiteLLM offers dedicated enterprise support.
|
||||
|
||||
This covers:
|
||||
- **Feature Prioritization**
|
||||
- **Custom Integrations**
|
||||
- **Professional Support - Dedicated discord + slack**
|
||||
- **Custom SLAs**
|
||||
|
||||
:::info
|
||||
|
||||
[Talk to founders](https://calendly.com/d/4mp-gd3-k5k/litellm-1-1-onboarding-chat)
|
||||
|
||||
:::
|
||||
|
|
@ -5,10 +5,14 @@ import TabItem from '@theme/TabItem';
|
|||
|
||||
https://github.com/BerriAI/litellm
|
||||
|
||||
import QuickStart from '../src/components/QuickStart.js'
|
||||
|
||||
## **Call 100+ LLMs using the same Input/Output Format**
|
||||
|
||||
- Translate inputs to provider's `completion`, `embedding`, and `image_generation` endpoints
|
||||
- [Consistent output](https://docs.litellm.ai/docs/completion/output), text responses will always be available at `['choices'][0]['message']['content']`
|
||||
- Retry/fallback logic across multiple deployments (e.g. Azure/OpenAI) - [Router](https://docs.litellm.ai/docs/routing)
|
||||
- Track spend & set budgets per project [OpenAI Proxy Server](https://docs.litellm.ai/docs/simple_proxy)
|
||||
|
||||
## Basic usage
|
||||
<a target="_blank" href="https://colab.research.google.com/github/BerriAI/litellm/blob/main/cookbook/liteLLM_Getting_Started.ipynb">
|
||||
<img src="https://colab.research.google.com/assets/colab-badge.svg" alt="Open In Colab"/>
|
||||
|
|
@ -157,9 +161,6 @@ response = completion(
|
|||
messages=[{ "content": "Hello, how are you?","role": "user"}],
|
||||
stream=True,
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
print(chunk)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
|
@ -177,9 +178,6 @@ response = completion(
|
|||
messages=[{ "content": "Hello, how are you?","role": "user"}],
|
||||
stream=True,
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
print(chunk)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
|
@ -199,9 +197,6 @@ response = completion(
|
|||
messages=[{ "content": "Hello, how are you?","role": "user"}],
|
||||
stream=True,
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
print(chunk)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
|
@ -222,9 +217,7 @@ response = completion(
|
|||
stream=True,
|
||||
)
|
||||
|
||||
|
||||
for chunk in response:
|
||||
print(chunk)
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
|
@ -246,9 +239,6 @@ response = completion(
|
|||
messages = [{ "content": "Hello, how are you?","role": "user"}],
|
||||
stream=True,
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
print(chunk)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
|
@ -265,9 +255,6 @@ response = completion(
|
|||
api_base="http://localhost:11434",
|
||||
stream=True,
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
print(chunk)
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="or" label="Openrouter">
|
||||
|
|
@ -284,9 +271,6 @@ response = completion(
|
|||
messages = [{ "content": "Hello, how are you?","role": "user"}],
|
||||
stream=True,
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
print(chunk)
|
||||
```
|
||||
</TabItem>
|
||||
|
||||
|
|
@ -327,34 +311,8 @@ litellm.success_callback = ["langfuse", "llmonitor"] # log input/output to langf
|
|||
response = completion(model="gpt-3.5-turbo", messages=[{"role": "user", "content": "Hi 👋 - i'm openai"}])
|
||||
```
|
||||
|
||||
## Calculate Costs, Usage, Latency
|
||||
|
||||
Pass the completion response to `litellm.completion_cost(completion_response=response)` and get the cost
|
||||
|
||||
```python
|
||||
from litellm import completion, completion_cost
|
||||
import os
|
||||
os.environ["OPENAI_API_KEY"] = "your-api-key"
|
||||
|
||||
response = completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{ "content": "Hello, how are you?","role": "user"}]
|
||||
)
|
||||
|
||||
cost = completion_cost(completion_response=response)
|
||||
print("Cost for completion call with gpt-3.5-turbo: ", f"${float(cost):.10f}")
|
||||
```
|
||||
|
||||
**Output**
|
||||
```shell
|
||||
Cost for completion call with gpt-3.5-turbo: $0.0000775000
|
||||
```
|
||||
|
||||
### Track Costs, Usage, Latency for streaming
|
||||
We use a custom callback function for this - more info on custom callbacks: https://docs.litellm.ai/docs/observability/custom_callback
|
||||
- We define a callback function to calculate cost `def track_cost_callback()`
|
||||
- In `def track_cost_callback()` we check if the stream is complete - `if "complete_streaming_response" in kwargs`
|
||||
- Use `litellm.completion_cost()` to calculate cost, once the stream is complete
|
||||
## Track Costs, Usage, Latency for streaming
|
||||
Use a callback function for this - more info on custom callbacks: https://docs.litellm.ai/docs/observability/custom_callback
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
|
@ -366,18 +324,8 @@ def track_cost_callback(
|
|||
start_time, end_time # start/end time
|
||||
):
|
||||
try:
|
||||
# check if it has collected an entire stream response
|
||||
if "complete_streaming_response" in kwargs:
|
||||
# for tracking streaming cost we pass the "messages" and the output_text to litellm.completion_cost
|
||||
completion_response=kwargs["complete_streaming_response"]
|
||||
input_text = kwargs["messages"]
|
||||
output_text = completion_response["choices"][0]["message"]["content"]
|
||||
response_cost = litellm.completion_cost(
|
||||
model = kwargs["model"],
|
||||
messages = input_text,
|
||||
completion=output_text
|
||||
)
|
||||
print("streaming response_cost", response_cost)
|
||||
response_cost = kwargs.get("response_cost", 0)
|
||||
print("streaming response_cost", response_cost)
|
||||
except:
|
||||
pass
|
||||
# set callback
|
||||
|
|
@ -400,6 +348,8 @@ response = completion(
|
|||
|
||||
Track spend across multiple projects/people
|
||||
|
||||

|
||||
|
||||
The proxy provides:
|
||||
1. [Hooks for auth](https://docs.litellm.ai/docs/proxy/virtual_keys#custom-auth)
|
||||
2. [Hooks for logging](https://docs.litellm.ai/docs/proxy/logging#step-1---create-your-custom-litellm-callback-class)
|
||||
|
|
@ -436,8 +386,7 @@ response = client.chat.completions.create(model="gpt-3.5-turbo", messages = [
|
|||
print(response)
|
||||
```
|
||||
|
||||
|
||||
## More details
|
||||
* [exception mapping](./exception_mapping.md)
|
||||
* [retries + model fallbacks for completion()](./completion/reliable_completions.md)
|
||||
* [tutorial for model fallbacks with completion()](./tutorials/fallbacks.md)
|
||||
* [proxy virtual keys & spend management](./tutorials/fallbacks.md)
|
||||
|
|
@ -27,6 +27,7 @@ Use just 2 lines of code, to instantly log your responses **across all providers
|
|||
Get your Langfuse API Keys from https://cloud.langfuse.com/
|
||||
```python
|
||||
litellm.success_callback = ["langfuse"]
|
||||
litellm.failure_callback = ["langfuse"] # logs errors to langfuse
|
||||
```
|
||||
```python
|
||||
# pip install langfuse
|
||||
|
|
|
|||
|
|
@ -74,6 +74,8 @@ response = litellm.completion(
|
|||
| gpt-4-32k | `completion('azure/<your deployment name>', messages)` |
|
||||
| gpt-4-32k-0314 | `completion('azure/<your deployment name>', messages)` |
|
||||
| gpt-4-32k-0613 | `completion('azure/<your deployment name>', messages)` |
|
||||
| gpt-4-1106-preview | `completion('azure/<your deployment name>', messages)` |
|
||||
| gpt-4-0125-preview | `completion('azure/<your deployment name>', messages)` |
|
||||
| gpt-3.5-turbo | `completion('azure/<your deployment name>', messages)` |
|
||||
| gpt-3.5-turbo-0301 | `completion('azure/<your deployment name>', messages)` |
|
||||
| gpt-3.5-turbo-0613 | `completion('azure/<your deployment name>', messages)` |
|
||||
|
|
|
|||
|
|
@ -197,7 +197,7 @@ response = completion(
|
|||
|
||||
### SSO Login (AWS Profile)
|
||||
- Set `AWS_PROFILE` environment variable
|
||||
- Make bedrock completion call
|
||||
- Make bedrock completion call
|
||||
```python
|
||||
import os
|
||||
from litellm import completion
|
||||
|
|
@ -208,11 +208,24 @@ response = completion(
|
|||
)
|
||||
```
|
||||
|
||||
### STS based Auth
|
||||
or pass `aws_profile_name`:
|
||||
|
||||
```python
|
||||
import os
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="bedrock/anthropic.claude-instant-v1",
|
||||
messages=[{ "content": "Hello, how are you?","role": "user"}],
|
||||
aws_profile_name="dev-profile",
|
||||
)
|
||||
```
|
||||
|
||||
### STS based Auth
|
||||
|
||||
- Set `aws_role_name` and `aws_session_name` in completion() / embedding() function
|
||||
|
||||
Make the bedrock completion call
|
||||
Make the bedrock completion call
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
|
|
|
|||
|
|
@ -246,6 +246,28 @@ model_list:
|
|||
$ litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
|
||||
## Set Azure `base_model` for cost tracking
|
||||
|
||||
**Problem**: Azure returns `gpt-4` in the response when `azure/gpt-4-1106-preview` is used. This leads to inaccurate cost tracking
|
||||
|
||||
**Solution** ✅ : Set `base_model` on your config so litellm uses the correct model for calculating azure cost
|
||||
|
||||
Example config with `base_model`
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: azure-gpt-3.5
|
||||
litellm_params:
|
||||
model: azure/chatgpt-v-2
|
||||
api_base: os.environ/AZURE_API_BASE
|
||||
api_key: os.environ/AZURE_API_KEY
|
||||
api_version: "2023-07-01-preview"
|
||||
model_info:
|
||||
base_model: azure/gpt-4-1106-preview
|
||||
```
|
||||
|
||||
You can view your cost once you set up [Virtual keys](https://docs.litellm.ai/docs/proxy/virtual_keys) or [custom_callbacks](https://docs.litellm.ai/docs/proxy/logging)
|
||||
|
||||
## Load API Keys
|
||||
|
||||
### Load API Keys from Environment
|
||||
|
|
|
|||
|
|
@ -8,16 +8,8 @@ Quick start CLI, Config, Docker
|
|||
LiteLLM Server manages:
|
||||
|
||||
* **Unified Interface**: Calling 100+ LLMs [Huggingface/Bedrock/TogetherAI/etc.](#other-supported-models) in the OpenAI `ChatCompletions` & `Completions` format
|
||||
* **Cost tracking**: Authentication, Spend Tracking & Budgets [Virtual Keys](https://docs.litellm.ai/docs/proxy/virtual_keys)
|
||||
* **Load Balancing**: between [Multiple Models](#multiple-models---quick-start) + [Deployments of the same model](#multiple-instances-of-1-model) - LiteLLM proxy can handle 1.5k+ requests/second during load tests.
|
||||
* **Cost tracking**: Authentication & Spend Tracking [Virtual Keys](#managing-auth---virtual-keys)
|
||||
|
||||
[**See LiteLLM Proxy code**](https://github.com/BerriAI/litellm/tree/main/litellm/proxy)
|
||||
|
||||
|
||||
#### 📖 Proxy Endpoints - [Swagger Docs](https://litellm-api.up.railway.app/)
|
||||
|
||||
|
||||
View all the supported args for the Proxy CLI [here](https://docs.litellm.ai/docs/simple_proxy#proxy-cli-arguments)
|
||||
|
||||
```shell
|
||||
$ pip install 'litellm[proxy]'
|
||||
|
|
@ -221,8 +213,38 @@ $ litellm --model command-nightly
|
|||
|
||||
</Tabs>
|
||||
|
||||
## Quick Start - LiteLLM Proxy + Config.yaml
|
||||
The config allows you to create a model list and set `api_base`, `max_tokens` (all litellm params). See more details about the config [here](https://docs.litellm.ai/docs/proxy/configs)
|
||||
|
||||
### Using LiteLLM Proxy - Curl Request, OpenAI Package, Langchain
|
||||
### Create a Config for LiteLLM Proxy
|
||||
Example config
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-3.5-turbo # user-facing model alias
|
||||
litellm_params: # all params accepted by litellm.completion() - https://docs.litellm.ai/docs/completion/input
|
||||
model: azure/<your-deployment-name>
|
||||
api_base: <your-azure-api-endpoint>
|
||||
api_key: <your-azure-api-key>
|
||||
- model_name: gpt-3.5-turbo
|
||||
litellm_params:
|
||||
model: azure/gpt-turbo-small-ca
|
||||
api_base: https://my-endpoint-canada-berri992.openai.azure.com/
|
||||
api_key: <your-azure-api-key>
|
||||
- model_name: vllm-model
|
||||
litellm_params:
|
||||
model: openai/<your-model-name>
|
||||
api_base: <your-api-base> # e.g. http://0.0.0.0:3000
|
||||
```
|
||||
|
||||
### Run proxy with config
|
||||
|
||||
```shell
|
||||
litellm --config your_config.yaml
|
||||
```
|
||||
|
||||
|
||||
## Using LiteLLM Proxy - Curl Request, OpenAI Package, Langchain
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="Curl" label="Curl Request">
|
||||
|
|
@ -330,37 +352,6 @@ print(query_result[:5])
|
|||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
||||
## Quick Start - LiteLLM Proxy + Config.yaml
|
||||
The config allows you to create a model list and set `api_base`, `max_tokens` (all litellm params). See more details about the config [here](https://docs.litellm.ai/docs/proxy/configs)
|
||||
|
||||
### Create a Config for LiteLLM Proxy
|
||||
Example config
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-3.5-turbo # user-facing model alias
|
||||
litellm_params: # all params accepted by litellm.completion() - https://docs.litellm.ai/docs/completion/input
|
||||
model: azure/<your-deployment-name>
|
||||
api_base: <your-azure-api-endpoint>
|
||||
api_key: <your-azure-api-key>
|
||||
- model_name: gpt-3.5-turbo
|
||||
litellm_params:
|
||||
model: azure/gpt-turbo-small-ca
|
||||
api_base: https://my-endpoint-canada-berri992.openai.azure.com/
|
||||
api_key: <your-azure-api-key>
|
||||
- model_name: vllm-model
|
||||
litellm_params:
|
||||
model: openai/<your-model-name>
|
||||
api_base: <your-api-base> # e.g. http://0.0.0.0:3000
|
||||
```
|
||||
|
||||
### Run proxy with config
|
||||
|
||||
```shell
|
||||
litellm --config your_config.yaml
|
||||
```
|
||||
|
||||
[**More Info**](./configs.md)
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -2,7 +2,7 @@ import Image from '@theme/IdealImage';
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# [BETA] Admin UI
|
||||
# 🔑 [BETA] Admin UI
|
||||
### **Create + delete keys through a UI**
|
||||
|
||||
:::info
|
||||
|
|
|
|||
|
|
@ -6,6 +6,7 @@ Grant other's temporary access to your proxy, with keys that expire after a set
|
|||
|
||||
:::info
|
||||
|
||||
- 🔑 [UI to Generate, Edit, Delete Keys (with SSO)](https://docs.litellm.ai/docs/proxy/ui)
|
||||
- [Deploy LiteLLM Proxy with Key Management](https://docs.litellm.ai/docs/proxy/deploy#deploy-with-database)
|
||||
- Dockerfile.database for LiteLLM Proxy + Key Management [here](https://github.com/BerriAI/litellm/blob/main/Dockerfile.database)
|
||||
|
||||
|
|
|
|||
|
|
@ -99,6 +99,12 @@ const config = {
|
|||
position: 'left',
|
||||
label: 'Docs',
|
||||
},
|
||||
{
|
||||
sidebarId: 'tutorialSidebar',
|
||||
position: 'left',
|
||||
label: 'Enterprise',
|
||||
to: "docs/enterprise"
|
||||
},
|
||||
{
|
||||
href: 'https://github.com/BerriAI/litellm',
|
||||
label: 'GitHub',
|
||||
|
|
|
|||
|
|
@ -98,7 +98,7 @@ const sidebars = {
|
|||
link: {
|
||||
type: 'generated-index',
|
||||
title: '💥 OpenAI Proxy Server',
|
||||
description: `Proxy Server to call 100+ LLMs in a unified interface, load balance deployments, track costs per user`,
|
||||
description: `Proxy Server to call 100+ LLMs in a unified interface & track spend, set budgets per virtual key/user`,
|
||||
slug: '/simple_proxy',
|
||||
},
|
||||
items: [
|
||||
|
|
|
|||
|
|
@ -8,6 +8,11 @@ https://github.com/BerriAI/litellm
|
|||
|
||||
## **Call 100+ LLMs using the same Input/Output Format**
|
||||
|
||||
- Translate inputs to provider's `completion`, `embedding`, and `image_generation` endpoints
|
||||
- [Consistent output](https://docs.litellm.ai/docs/completion/output), text responses will always be available at `['choices'][0]['message']['content']`
|
||||
- Retry/fallback logic across multiple deployments (e.g. Azure/OpenAI) - [Router](https://docs.litellm.ai/docs/routing)
|
||||
- Track spend & set budgets per project [OpenAI Proxy Server](https://docs.litellm.ai/docs/simple_proxy)
|
||||
|
||||
## Basic usage
|
||||
<a target="_blank" href="https://colab.research.google.com/github/BerriAI/litellm/blob/main/cookbook/liteLLM_Getting_Started.ipynb">
|
||||
<img src="https://colab.research.google.com/assets/colab-badge.svg" alt="Open In Colab"/>
|
||||
|
|
@ -306,30 +311,7 @@ litellm.success_callback = ["langfuse", "llmonitor"] # log input/output to langf
|
|||
response = completion(model="gpt-3.5-turbo", messages=[{"role": "user", "content": "Hi 👋 - i'm openai"}])
|
||||
```
|
||||
|
||||
## Calculate Costs, Usage, Latency
|
||||
|
||||
Pass the completion response to `litellm.completion_cost(completion_response=response)` and get the cost
|
||||
|
||||
```python
|
||||
from litellm import completion, completion_cost
|
||||
import os
|
||||
os.environ["OPENAI_API_KEY"] = "your-api-key"
|
||||
|
||||
response = completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{ "content": "Hello, how are you?","role": "user"}]
|
||||
)
|
||||
|
||||
cost = completion_cost(completion_response=response)
|
||||
print("Cost for completion call with gpt-3.5-turbo: ", f"${float(cost):.10f}")
|
||||
```
|
||||
|
||||
**Output**
|
||||
```shell
|
||||
Cost for completion call with gpt-3.5-turbo: $0.0000775000
|
||||
```
|
||||
|
||||
### Track Costs, Usage, Latency for streaming
|
||||
## Track Costs, Usage, Latency for streaming
|
||||
Use a callback function for this - more info on custom callbacks: https://docs.litellm.ai/docs/observability/custom_callback
|
||||
|
||||
```python
|
||||
|
|
@ -342,18 +324,8 @@ def track_cost_callback(
|
|||
start_time, end_time # start/end time
|
||||
):
|
||||
try:
|
||||
# check if it has collected an entire stream response
|
||||
if "complete_streaming_response" in kwargs:
|
||||
# for tracking streaming cost we pass the "messages" and the output_text to litellm.completion_cost
|
||||
completion_response=kwargs["complete_streaming_response"]
|
||||
input_text = kwargs["messages"]
|
||||
output_text = completion_response["choices"][0]["message"]["content"]
|
||||
response_cost = litellm.completion_cost(
|
||||
model = kwargs["model"],
|
||||
messages = input_text,
|
||||
completion=output_text
|
||||
)
|
||||
print("streaming response_cost", response_cost)
|
||||
response_cost = kwargs.get("response_cost", 0)
|
||||
print("streaming response_cost", response_cost)
|
||||
except:
|
||||
pass
|
||||
# set callback
|
||||
|
|
@ -372,13 +344,12 @@ response = completion(
|
|||
)
|
||||
```
|
||||
|
||||
|
||||
Need a dedicated key? Email us @ krrish@berri.ai
|
||||
|
||||
## OpenAI Proxy
|
||||
|
||||
Track spend across multiple projects/people
|
||||
|
||||

|
||||
|
||||
The proxy provides:
|
||||
1. [Hooks for auth](https://docs.litellm.ai/docs/proxy/virtual_keys#custom-auth)
|
||||
2. [Hooks for logging](https://docs.litellm.ai/docs/proxy/logging#step-1---create-your-custom-litellm-callback-class)
|
||||
|
|
@ -418,4 +389,4 @@ print(response)
|
|||
## More details
|
||||
* [exception mapping](./exception_mapping.md)
|
||||
* [retries + model fallbacks for completion()](./completion/reliable_completions.md)
|
||||
* [tutorial for model fallbacks with completion()](./tutorials/fallbacks.md)
|
||||
* [proxy virtual keys & spend management](./tutorials/fallbacks.md)
|
||||
|
|
@ -427,10 +427,16 @@ class RedisSemanticCache(BaseCache):
|
|||
else []
|
||||
)
|
||||
if llm_router is not None and self.embedding_model in router_model_names:
|
||||
user_api_key = kwargs.get("metadata", {}).get("user_api_key", "")
|
||||
embedding_response = await llm_router.aembedding(
|
||||
model=self.embedding_model,
|
||||
input=prompt,
|
||||
cache={"no-store": True, "no-cache": True},
|
||||
metadata={
|
||||
"user_api_key": user_api_key,
|
||||
"semantic-cache-embedding": True,
|
||||
"trace_id": kwargs.get("metadata", {}).get("trace_id", None),
|
||||
},
|
||||
)
|
||||
else:
|
||||
# convert to embedding
|
||||
|
|
@ -476,10 +482,16 @@ class RedisSemanticCache(BaseCache):
|
|||
else []
|
||||
)
|
||||
if llm_router is not None and self.embedding_model in router_model_names:
|
||||
user_api_key = kwargs.get("metadata", {}).get("user_api_key", "")
|
||||
embedding_response = await llm_router.aembedding(
|
||||
model=self.embedding_model,
|
||||
input=prompt,
|
||||
cache={"no-store": True, "no-cache": True},
|
||||
metadata={
|
||||
"user_api_key": user_api_key,
|
||||
"semantic-cache-embedding": True,
|
||||
"trace_id": kwargs.get("metadata", {}).get("trace_id", None),
|
||||
},
|
||||
)
|
||||
else:
|
||||
# convert to embedding
|
||||
|
|
|
|||
|
|
@ -266,37 +266,33 @@ class LangFuseLogger:
|
|||
|
||||
trace = self.Langfuse.trace(**trace_params)
|
||||
|
||||
if level == "ERROR":
|
||||
trace.generation(
|
||||
level="ERROR", # can be any of DEBUG, DEFAULT, WARNING or ERROR
|
||||
status_message=output, # can be any string (e.g. stringified stack trace or error body)
|
||||
)
|
||||
print(f"SUCCESSFULLY LOGGED ERROR")
|
||||
else:
|
||||
# get generation_id
|
||||
generation_id = None
|
||||
if (
|
||||
response_obj is not None
|
||||
and response_obj.get("id", None) is not None
|
||||
):
|
||||
generation_id = litellm.utils.get_logging_id(
|
||||
start_time, response_obj
|
||||
)
|
||||
trace.generation(
|
||||
name=generation_name,
|
||||
id=metadata.get("generation_id", generation_id),
|
||||
startTime=start_time,
|
||||
endTime=end_time,
|
||||
model=kwargs["model"],
|
||||
modelParameters=optional_params,
|
||||
input=input,
|
||||
output=output,
|
||||
usage={
|
||||
"prompt_tokens": response_obj["usage"]["prompt_tokens"],
|
||||
"completion_tokens": response_obj["usage"]["completion_tokens"],
|
||||
"total_cost": cost if supports_costs else None,
|
||||
},
|
||||
metadata=metadata,
|
||||
)
|
||||
generation_id = None
|
||||
usage = None
|
||||
if response_obj is not None and response_obj.get("id", None) is not None:
|
||||
generation_id = litellm.utils.get_logging_id(start_time, response_obj)
|
||||
usage = {
|
||||
"prompt_tokens": response_obj["usage"]["prompt_tokens"],
|
||||
"completion_tokens": response_obj["usage"]["completion_tokens"],
|
||||
"total_cost": cost if supports_costs else None,
|
||||
}
|
||||
|
||||
generation_params = {
|
||||
"name": generation_name,
|
||||
"id": metadata.get("generation_id", generation_id),
|
||||
"startTime": start_time,
|
||||
"endTime": end_time,
|
||||
"model": kwargs["model"],
|
||||
"modelParameters": optional_params,
|
||||
"input": input,
|
||||
"output": output,
|
||||
"usage": usage,
|
||||
"metadata": metadata,
|
||||
"level": level,
|
||||
}
|
||||
|
||||
if output is not None and isinstance(output, str) and level == "ERROR":
|
||||
generation_params["statusMessage"] = output
|
||||
|
||||
trace.generation(**generation_params)
|
||||
except Exception as e:
|
||||
print(f"Langfuse Layer Error - {traceback.format_exc()}")
|
||||
|
|
|
|||
|
|
@ -356,6 +356,7 @@ def init_bedrock_client(
|
|||
aws_region_name: Optional[str] = None,
|
||||
aws_bedrock_runtime_endpoint: Optional[str] = None,
|
||||
aws_session_name: Optional[str] = None,
|
||||
aws_profile_name: Optional[str] = None,
|
||||
aws_role_name: Optional[str] = None,
|
||||
timeout: Optional[int] = None,
|
||||
):
|
||||
|
|
@ -371,6 +372,7 @@ def init_bedrock_client(
|
|||
aws_region_name,
|
||||
aws_bedrock_runtime_endpoint,
|
||||
aws_session_name,
|
||||
aws_profile_name,
|
||||
aws_role_name,
|
||||
]
|
||||
|
||||
|
|
@ -385,6 +387,7 @@ def init_bedrock_client(
|
|||
aws_region_name,
|
||||
aws_bedrock_runtime_endpoint,
|
||||
aws_session_name,
|
||||
aws_profile_name,
|
||||
aws_role_name,
|
||||
) = params_to_check
|
||||
|
||||
|
|
@ -450,6 +453,15 @@ def init_bedrock_client(
|
|||
endpoint_url=endpoint_url,
|
||||
config=config,
|
||||
)
|
||||
elif aws_profile_name is not None:
|
||||
# uses auth values from AWS profile usually stored in ~/.aws/credentials
|
||||
|
||||
client = boto3.Session(profile_name=aws_profile_name).client(
|
||||
service_name="bedrock-runtime",
|
||||
region_name=region_name,
|
||||
endpoint_url=endpoint_url,
|
||||
config=config,
|
||||
)
|
||||
else:
|
||||
# aws_access_key_id is None, assume user is trying to auth using env variables
|
||||
# boto3 automatically reads env variables
|
||||
|
|
@ -523,6 +535,7 @@ def completion(
|
|||
aws_region_name = optional_params.pop("aws_region_name", None)
|
||||
aws_role_name = optional_params.pop("aws_role_name", None)
|
||||
aws_session_name = optional_params.pop("aws_session_name", None)
|
||||
aws_profile_name = optional_params.pop("aws_profile_name", None)
|
||||
aws_bedrock_runtime_endpoint = optional_params.pop(
|
||||
"aws_bedrock_runtime_endpoint", None
|
||||
)
|
||||
|
|
@ -539,6 +552,7 @@ def completion(
|
|||
aws_bedrock_runtime_endpoint=aws_bedrock_runtime_endpoint,
|
||||
aws_role_name=aws_role_name,
|
||||
aws_session_name=aws_session_name,
|
||||
aws_profile_name=aws_profile_name,
|
||||
)
|
||||
|
||||
model = model
|
||||
|
|
@ -725,6 +739,8 @@ def completion(
|
|||
try:
|
||||
if len(outputText) > 0:
|
||||
model_response["choices"][0]["message"]["content"] = outputText
|
||||
else:
|
||||
raise Exception()
|
||||
except:
|
||||
raise BedrockError(
|
||||
message=json.dumps(outputText),
|
||||
|
|
|
|||
|
|
@ -222,6 +222,7 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
custom_prompt_dict: dict = {},
|
||||
client=None,
|
||||
organization: Optional[str] = None,
|
||||
custom_llm_provider: Optional[str] = None,
|
||||
):
|
||||
super().completion()
|
||||
exception_mapping_worked = False
|
||||
|
|
@ -236,6 +237,14 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
status_code=422, message=f"Timeout needs to be a float"
|
||||
)
|
||||
|
||||
if custom_llm_provider == "mistral":
|
||||
# check if message content passed in as list, and not string
|
||||
messages = prompt_factory(
|
||||
model=model,
|
||||
messages=messages,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
)
|
||||
|
||||
for _ in range(
|
||||
2
|
||||
): # if call fails due to alternating messages, retry with reformatted message
|
||||
|
|
@ -325,12 +334,13 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
model_response_object=model_response,
|
||||
)
|
||||
except Exception as e:
|
||||
if "Conversation roles must alternate user/assistant" in str(
|
||||
e
|
||||
) or "user and assistant roles should be alternating" in str(e):
|
||||
if (
|
||||
"Conversation roles must alternate user/assistant" in str(e)
|
||||
or "user and assistant roles should be alternating" in str(e)
|
||||
) and messages is not None:
|
||||
# reformat messages to ensure user/assistant are alternating, if there's either 2 consecutive 'user' messages or 2 consecutive 'assistant' message, add a blank 'user' or 'assistant' message to ensure compatibility
|
||||
new_messages = []
|
||||
for i in range(len(messages) - 1):
|
||||
for i in range(len(messages) - 1): # type: ignore
|
||||
new_messages.append(messages[i])
|
||||
if messages[i]["role"] == messages[i + 1]["role"]:
|
||||
if messages[i]["role"] == "user":
|
||||
|
|
@ -341,7 +351,9 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
new_messages.append({"role": "user", "content": ""})
|
||||
new_messages.append(messages[-1])
|
||||
messages = new_messages
|
||||
elif "Last message must have role `user`" in str(e):
|
||||
elif (
|
||||
"Last message must have role `user`" in str(e)
|
||||
) and messages is not None:
|
||||
new_messages = messages
|
||||
new_messages.append({"role": "user", "content": ""})
|
||||
messages = new_messages
|
||||
|
|
|
|||
|
|
@ -116,6 +116,28 @@ def mistral_instruct_pt(messages):
|
|||
return prompt
|
||||
|
||||
|
||||
def mistral_api_pt(messages):
|
||||
"""
|
||||
- handles scenario where content is list and not string
|
||||
- content list is just text, and no images
|
||||
- if image passed in, then just return as is (user-intended)
|
||||
|
||||
Motivation: mistral api doesn't support content as a list
|
||||
"""
|
||||
new_messages = []
|
||||
for m in messages:
|
||||
texts = ""
|
||||
if isinstance(m["content"], list):
|
||||
for c in m["content"]:
|
||||
if c["type"] == "image_url":
|
||||
return messages
|
||||
elif c["type"] == "text" and isinstance(c["text"], str):
|
||||
texts += c["text"]
|
||||
new_m = {"role": m["role"], "content": texts}
|
||||
new_messages.append(new_m)
|
||||
return new_messages
|
||||
|
||||
|
||||
# Falcon prompt template - from https://github.com/lm-sys/FastChat/blob/main/fastchat/conversation.py#L110
|
||||
def falcon_instruct_pt(messages):
|
||||
prompt = ""
|
||||
|
|
@ -612,6 +634,8 @@ def prompt_factory(
|
|||
return _gemini_vision_convert_messages(messages=messages)
|
||||
else:
|
||||
return gemini_text_image_pt(messages=messages)
|
||||
elif custom_llm_provider == "mistral":
|
||||
return mistral_api_pt(messages=messages)
|
||||
try:
|
||||
if "meta-llama/llama-2" in model and "chat" in model:
|
||||
return llama_2_chat_pt(messages=messages)
|
||||
|
|
|
|||
|
|
@ -10,7 +10,6 @@
|
|||
import os, openai, sys, json, inspect, uuid, datetime, threading
|
||||
from typing import Any, Literal, Union
|
||||
from functools import partial
|
||||
|
||||
import dotenv, traceback, random, asyncio, time, contextvars
|
||||
from copy import deepcopy
|
||||
import httpx
|
||||
|
|
@ -31,6 +30,7 @@ from litellm.utils import (
|
|||
get_llm_provider,
|
||||
get_api_key,
|
||||
mock_completion_streaming_obj,
|
||||
async_mock_completion_streaming_obj,
|
||||
convert_to_model_response_object,
|
||||
token_counter,
|
||||
Usage,
|
||||
|
|
@ -307,6 +307,7 @@ def mock_completion(
|
|||
messages: List,
|
||||
stream: Optional[bool] = False,
|
||||
mock_response: str = "This is a mock request",
|
||||
logging=None,
|
||||
**kwargs,
|
||||
):
|
||||
"""
|
||||
|
|
@ -335,6 +336,15 @@ def mock_completion(
|
|||
model_response = ModelResponse(stream=stream)
|
||||
if stream is True:
|
||||
# don't try to access stream object,
|
||||
if kwargs.get("acompletion", False) == True:
|
||||
return CustomStreamWrapper(
|
||||
completion_stream=async_mock_completion_streaming_obj(
|
||||
model_response, mock_response=mock_response, model=model
|
||||
),
|
||||
model=model,
|
||||
custom_llm_provider="openai",
|
||||
logging_obj=logging,
|
||||
)
|
||||
response = mock_completion_streaming_obj(
|
||||
model_response, mock_response=mock_response, model=model
|
||||
)
|
||||
|
|
@ -717,7 +727,12 @@ def completion(
|
|||
)
|
||||
if mock_response:
|
||||
return mock_completion(
|
||||
model, messages, stream=stream, mock_response=mock_response
|
||||
model,
|
||||
messages,
|
||||
stream=stream,
|
||||
mock_response=mock_response,
|
||||
logging=logging,
|
||||
acompletion=acompletion,
|
||||
)
|
||||
if custom_llm_provider == "azure":
|
||||
# azure configs
|
||||
|
|
|
|||
|
|
@ -8,6 +8,15 @@
|
|||
"litellm_provider": "openai",
|
||||
"mode": "chat"
|
||||
},
|
||||
"gpt-4-turbo-preview": {
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 8192,
|
||||
"max_output_tokens": 4096,
|
||||
"input_cost_per_token": 0.00001,
|
||||
"output_cost_per_token": 0.00003,
|
||||
"litellm_provider": "openai",
|
||||
"mode": "chat"
|
||||
},
|
||||
"gpt-4-0314": {
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 8192,
|
||||
|
|
@ -243,6 +252,15 @@
|
|||
"output_cost_per_pixel": 0.0,
|
||||
"litellm_provider": "openai"
|
||||
},
|
||||
"azure/gpt-4-0125-preview": {
|
||||
"max_tokens": 128000,
|
||||
"max_input_tokens": 128000,
|
||||
"max_output_tokens": 4096,
|
||||
"input_cost_per_token": 0.00001,
|
||||
"output_cost_per_token": 0.00003,
|
||||
"litellm_provider": "azure",
|
||||
"mode": "chat"
|
||||
},
|
||||
"azure/gpt-4-1106-preview": {
|
||||
"max_tokens": 128000,
|
||||
"max_input_tokens": 128000,
|
||||
|
|
|
|||
File diff suppressed because one or more lines are too long
|
|
@ -1 +1 @@
|
|||
(self.webpackChunk_N_E=self.webpackChunk_N_E||[]).push([[185],{11837:function(n,e,t){Promise.resolve().then(t.t.bind(t,99646,23)),Promise.resolve().then(t.t.bind(t,63385,23))},63385:function(){},99646:function(n){n.exports={style:{fontFamily:"'__Inter_c23dc8', '__Inter_Fallback_c23dc8'",fontStyle:"normal"},className:"__className_c23dc8"}}},function(n){n.O(0,[971,69,744],function(){return n(n.s=11837)}),_N_E=n.O()}]);
|
||||
(self.webpackChunk_N_E=self.webpackChunk_N_E||[]).push([[185],{87421:function(n,e,t){Promise.resolve().then(t.t.bind(t,99646,23)),Promise.resolve().then(t.t.bind(t,63385,23))},63385:function(){},99646:function(n){n.exports={style:{fontFamily:"'__Inter_c23dc8', '__Inter_Fallback_c23dc8'",fontStyle:"normal"},className:"__className_c23dc8"}}},function(n){n.O(0,[971,69,744],function(){return n(n.s=87421)}),_N_E=n.O()}]);
|
||||
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
|
|
@ -1 +1 @@
|
|||
(self.webpackChunk_N_E=self.webpackChunk_N_E||[]).push([[744],{70377:function(e,n,t){Promise.resolve().then(t.t.bind(t,47690,23)),Promise.resolve().then(t.t.bind(t,48955,23)),Promise.resolve().then(t.t.bind(t,5613,23)),Promise.resolve().then(t.t.bind(t,11902,23)),Promise.resolve().then(t.t.bind(t,31778,23)),Promise.resolve().then(t.t.bind(t,77831,23))}},function(e){var n=function(n){return e(e.s=n)};e.O(0,[971,69],function(){return n(35317),n(70377)}),_N_E=e.O()}]);
|
||||
(self.webpackChunk_N_E=self.webpackChunk_N_E||[]).push([[744],{32028:function(e,n,t){Promise.resolve().then(t.t.bind(t,47690,23)),Promise.resolve().then(t.t.bind(t,48955,23)),Promise.resolve().then(t.t.bind(t,5613,23)),Promise.resolve().then(t.t.bind(t,11902,23)),Promise.resolve().then(t.t.bind(t,31778,23)),Promise.resolve().then(t.t.bind(t,77831,23))}},function(e){var n=function(n){return e(e.s=n)};e.O(0,[971,69],function(){return n(35317),n(32028)}),_N_E=e.O()}]);
|
||||
|
|
@ -1 +1 @@
|
|||
!function(){"use strict";var e,t,n,r,o,u,i,c,f,a={},l={};function d(e){var t=l[e];if(void 0!==t)return t.exports;var n=l[e]={id:e,loaded:!1,exports:{}},r=!0;try{a[e](n,n.exports,d),r=!1}finally{r&&delete l[e]}return n.loaded=!0,n.exports}d.m=a,e=[],d.O=function(t,n,r,o){if(n){o=o||0;for(var u=e.length;u>0&&e[u-1][2]>o;u--)e[u]=e[u-1];e[u]=[n,r,o];return}for(var i=1/0,u=0;u<e.length;u++){for(var n=e[u][0],r=e[u][1],o=e[u][2],c=!0,f=0;f<n.length;f++)i>=o&&Object.keys(d.O).every(function(e){return d.O[e](n[f])})?n.splice(f--,1):(c=!1,o<i&&(i=o));if(c){e.splice(u--,1);var a=r();void 0!==a&&(t=a)}}return t},d.n=function(e){var t=e&&e.__esModule?function(){return e.default}:function(){return e};return d.d(t,{a:t}),t},n=Object.getPrototypeOf?function(e){return Object.getPrototypeOf(e)}:function(e){return e.__proto__},d.t=function(e,r){if(1&r&&(e=this(e)),8&r||"object"==typeof e&&e&&(4&r&&e.__esModule||16&r&&"function"==typeof e.then))return e;var o=Object.create(null);d.r(o);var u={};t=t||[null,n({}),n([]),n(n)];for(var i=2&r&&e;"object"==typeof i&&!~t.indexOf(i);i=n(i))Object.getOwnPropertyNames(i).forEach(function(t){u[t]=function(){return e[t]}});return u.default=function(){return e},d.d(o,u),o},d.d=function(e,t){for(var n in t)d.o(t,n)&&!d.o(e,n)&&Object.defineProperty(e,n,{enumerable:!0,get:t[n]})},d.f={},d.e=function(e){return Promise.all(Object.keys(d.f).reduce(function(t,n){return d.f[n](e,t),t},[]))},d.u=function(e){},d.miniCssF=function(e){return"static/css/a6a9860a7fe022a9.css"},d.g=function(){if("object"==typeof globalThis)return globalThis;try{return this||Function("return this")()}catch(e){if("object"==typeof window)return window}}(),d.o=function(e,t){return Object.prototype.hasOwnProperty.call(e,t)},r={},o="_N_E:",d.l=function(e,t,n,u){if(r[e]){r[e].push(t);return}if(void 0!==n)for(var i,c,f=document.getElementsByTagName("script"),a=0;a<f.length;a++){var l=f[a];if(l.getAttribute("src")==e||l.getAttribute("data-webpack")==o+n){i=l;break}}i||(c=!0,(i=document.createElement("script")).charset="utf-8",i.timeout=120,d.nc&&i.setAttribute("nonce",d.nc),i.setAttribute("data-webpack",o+n),i.src=d.tu(e)),r[e]=[t];var s=function(t,n){i.onerror=i.onload=null,clearTimeout(p);var o=r[e];if(delete r[e],i.parentNode&&i.parentNode.removeChild(i),o&&o.forEach(function(e){return e(n)}),t)return t(n)},p=setTimeout(s.bind(null,void 0,{type:"timeout",target:i}),12e4);i.onerror=s.bind(null,i.onerror),i.onload=s.bind(null,i.onload),c&&document.head.appendChild(i)},d.r=function(e){"undefined"!=typeof Symbol&&Symbol.toStringTag&&Object.defineProperty(e,Symbol.toStringTag,{value:"Module"}),Object.defineProperty(e,"__esModule",{value:!0})},d.nmd=function(e){return e.paths=[],e.children||(e.children=[]),e},d.tt=function(){return void 0===u&&(u={createScriptURL:function(e){return e}},"undefined"!=typeof trustedTypes&&trustedTypes.createPolicy&&(u=trustedTypes.createPolicy("nextjs#bundler",u))),u},d.tu=function(e){return d.tt().createScriptURL(e)},d.p="/ui/_next/",i={272:0},d.f.j=function(e,t){var n=d.o(i,e)?i[e]:void 0;if(0!==n){if(n)t.push(n[2]);else if(272!=e){var r=new Promise(function(t,r){n=i[e]=[t,r]});t.push(n[2]=r);var o=d.p+d.u(e),u=Error();d.l(o,function(t){if(d.o(i,e)&&(0!==(n=i[e])&&(i[e]=void 0),n)){var r=t&&("load"===t.type?"missing":t.type),o=t&&t.target&&t.target.src;u.message="Loading chunk "+e+" failed.\n("+r+": "+o+")",u.name="ChunkLoadError",u.type=r,u.request=o,n[1](u)}},"chunk-"+e,e)}else i[e]=0}},d.O.j=function(e){return 0===i[e]},c=function(e,t){var n,r,o=t[0],u=t[1],c=t[2],f=0;if(o.some(function(e){return 0!==i[e]})){for(n in u)d.o(u,n)&&(d.m[n]=u[n]);if(c)var a=c(d)}for(e&&e(t);f<o.length;f++)r=o[f],d.o(i,r)&&i[r]&&i[r][0](),i[r]=0;return d.O(a)},(f=self.webpackChunk_N_E=self.webpackChunk_N_E||[]).forEach(c.bind(null,0)),f.push=c.bind(null,f.push.bind(f))}();
|
||||
!function(){"use strict";var e,t,n,r,o,u,i,c,f,a={},l={};function d(e){var t=l[e];if(void 0!==t)return t.exports;var n=l[e]={id:e,loaded:!1,exports:{}},r=!0;try{a[e](n,n.exports,d),r=!1}finally{r&&delete l[e]}return n.loaded=!0,n.exports}d.m=a,e=[],d.O=function(t,n,r,o){if(n){o=o||0;for(var u=e.length;u>0&&e[u-1][2]>o;u--)e[u]=e[u-1];e[u]=[n,r,o];return}for(var i=1/0,u=0;u<e.length;u++){for(var n=e[u][0],r=e[u][1],o=e[u][2],c=!0,f=0;f<n.length;f++)i>=o&&Object.keys(d.O).every(function(e){return d.O[e](n[f])})?n.splice(f--,1):(c=!1,o<i&&(i=o));if(c){e.splice(u--,1);var a=r();void 0!==a&&(t=a)}}return t},d.n=function(e){var t=e&&e.__esModule?function(){return e.default}:function(){return e};return d.d(t,{a:t}),t},n=Object.getPrototypeOf?function(e){return Object.getPrototypeOf(e)}:function(e){return e.__proto__},d.t=function(e,r){if(1&r&&(e=this(e)),8&r||"object"==typeof e&&e&&(4&r&&e.__esModule||16&r&&"function"==typeof e.then))return e;var o=Object.create(null);d.r(o);var u={};t=t||[null,n({}),n([]),n(n)];for(var i=2&r&&e;"object"==typeof i&&!~t.indexOf(i);i=n(i))Object.getOwnPropertyNames(i).forEach(function(t){u[t]=function(){return e[t]}});return u.default=function(){return e},d.d(o,u),o},d.d=function(e,t){for(var n in t)d.o(t,n)&&!d.o(e,n)&&Object.defineProperty(e,n,{enumerable:!0,get:t[n]})},d.f={},d.e=function(e){return Promise.all(Object.keys(d.f).reduce(function(t,n){return d.f[n](e,t),t},[]))},d.u=function(e){},d.miniCssF=function(e){return"static/css/173c5a76ba57a3b8.css"},d.g=function(){if("object"==typeof globalThis)return globalThis;try{return this||Function("return this")()}catch(e){if("object"==typeof window)return window}}(),d.o=function(e,t){return Object.prototype.hasOwnProperty.call(e,t)},r={},o="_N_E:",d.l=function(e,t,n,u){if(r[e]){r[e].push(t);return}if(void 0!==n)for(var i,c,f=document.getElementsByTagName("script"),a=0;a<f.length;a++){var l=f[a];if(l.getAttribute("src")==e||l.getAttribute("data-webpack")==o+n){i=l;break}}i||(c=!0,(i=document.createElement("script")).charset="utf-8",i.timeout=120,d.nc&&i.setAttribute("nonce",d.nc),i.setAttribute("data-webpack",o+n),i.src=d.tu(e)),r[e]=[t];var s=function(t,n){i.onerror=i.onload=null,clearTimeout(p);var o=r[e];if(delete r[e],i.parentNode&&i.parentNode.removeChild(i),o&&o.forEach(function(e){return e(n)}),t)return t(n)},p=setTimeout(s.bind(null,void 0,{type:"timeout",target:i}),12e4);i.onerror=s.bind(null,i.onerror),i.onload=s.bind(null,i.onload),c&&document.head.appendChild(i)},d.r=function(e){"undefined"!=typeof Symbol&&Symbol.toStringTag&&Object.defineProperty(e,Symbol.toStringTag,{value:"Module"}),Object.defineProperty(e,"__esModule",{value:!0})},d.nmd=function(e){return e.paths=[],e.children||(e.children=[]),e},d.tt=function(){return void 0===u&&(u={createScriptURL:function(e){return e}},"undefined"!=typeof trustedTypes&&trustedTypes.createPolicy&&(u=trustedTypes.createPolicy("nextjs#bundler",u))),u},d.tu=function(e){return d.tt().createScriptURL(e)},d.p="/ui/_next/",i={272:0},d.f.j=function(e,t){var n=d.o(i,e)?i[e]:void 0;if(0!==n){if(n)t.push(n[2]);else if(272!=e){var r=new Promise(function(t,r){n=i[e]=[t,r]});t.push(n[2]=r);var o=d.p+d.u(e),u=Error();d.l(o,function(t){if(d.o(i,e)&&(0!==(n=i[e])&&(i[e]=void 0),n)){var r=t&&("load"===t.type?"missing":t.type),o=t&&t.target&&t.target.src;u.message="Loading chunk "+e+" failed.\n("+r+": "+o+")",u.name="ChunkLoadError",u.type=r,u.request=o,n[1](u)}},"chunk-"+e,e)}else i[e]=0}},d.O.j=function(e){return 0===i[e]},c=function(e,t){var n,r,o=t[0],u=t[1],c=t[2],f=0;if(o.some(function(e){return 0!==i[e]})){for(n in u)d.o(u,n)&&(d.m[n]=u[n]);if(c)var a=c(d)}for(e&&e(t);f<o.length;f++)r=o[f],d.o(i,r)&&i[r]&&i[r][0](),i[r]=0;return d.O(a)},(f=self.webpackChunk_N_E=self.webpackChunk_N_E||[]).forEach(c.bind(null,0)),f.push=c.bind(null,f.push.bind(f))}();
|
||||
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
|
|
@ -1,7 +1,7 @@
|
|||
2:"$Sreact.suspense"
|
||||
3:I[27680,["787","static/chunks/787-5bb33960644f5c7c.js","931","static/chunks/app/page-7f03ccc8529ada97.js"],""]
|
||||
3:I[42989,["787","static/chunks/787-5bb33960644f5c7c.js","931","static/chunks/app/page-b1e8aae39e9306e9.js"],""]
|
||||
4:I[5613,[],""]
|
||||
5:I[31778,[],""]
|
||||
0:["p5gDwQBbgW8D3Uz3lgoZg",[[["",{"children":["__PAGE__",{}]},"$undefined","$undefined",true],["",{"children":["__PAGE__",{},["$L1",["$","$2",null,{"fallback":["$","div",null,{"children":"Loading..."}],"children":["$","div",null,{"className":"flex min-h-screen flex-col ","children":["$","$L3",null,{}]}]}],null]]},[null,["$","html",null,{"lang":"en","children":["$","body",null,{"className":"__className_c23dc8","children":["$","$L4",null,{"parallelRouterKey":"children","segmentPath":["children"],"loading":"$undefined","loadingStyles":"$undefined","loadingScripts":"$undefined","hasLoading":false,"error":"$undefined","errorStyles":"$undefined","errorScripts":"$undefined","template":["$","$L5",null,{}],"templateStyles":"$undefined","templateScripts":"$undefined","notFound":[["$","title",null,{"children":"404: This page could not be found."}],["$","div",null,{"style":{"fontFamily":"system-ui,\"Segoe UI\",Roboto,Helvetica,Arial,sans-serif,\"Apple Color Emoji\",\"Segoe UI Emoji\"","height":"100vh","textAlign":"center","display":"flex","flexDirection":"column","alignItems":"center","justifyContent":"center"},"children":["$","div",null,{"children":[["$","style",null,{"dangerouslySetInnerHTML":{"__html":"body{color:#000;background:#fff;margin:0}.next-error-h1{border-right:1px solid rgba(0,0,0,.3)}@media (prefers-color-scheme:dark){body{color:#fff;background:#000}.next-error-h1{border-right:1px solid rgba(255,255,255,.3)}}"}}],["$","h1",null,{"className":"next-error-h1","style":{"display":"inline-block","margin":"0 20px 0 0","padding":"0 23px 0 0","fontSize":24,"fontWeight":500,"verticalAlign":"top","lineHeight":"49px"},"children":"404"}],["$","div",null,{"style":{"display":"inline-block"},"children":["$","h2",null,{"style":{"fontSize":14,"fontWeight":400,"lineHeight":"49px","margin":0},"children":"This page could not be found."}]}]]}]}]],"notFoundStyles":[],"styles":null}]}]}],null]],[[["$","link","0",{"rel":"stylesheet","href":"/ui/_next/static/css/a6a9860a7fe022a9.css","precedence":"next","crossOrigin":""}]],"$L6"]]]]
|
||||
0:["Ul7bzKEbTPs-NwnRJpbmM",[[["",{"children":["__PAGE__",{}]},"$undefined","$undefined",true],["",{"children":["__PAGE__",{},["$L1",["$","$2",null,{"fallback":["$","div",null,{"children":"Loading..."}],"children":["$","div",null,{"className":"flex min-h-screen flex-col ","children":["$","$L3",null,{}]}]}],null]]},[null,["$","html",null,{"lang":"en","children":["$","body",null,{"className":"__className_c23dc8","children":["$","$L4",null,{"parallelRouterKey":"children","segmentPath":["children"],"loading":"$undefined","loadingStyles":"$undefined","loadingScripts":"$undefined","hasLoading":false,"error":"$undefined","errorStyles":"$undefined","errorScripts":"$undefined","template":["$","$L5",null,{}],"templateStyles":"$undefined","templateScripts":"$undefined","notFound":[["$","title",null,{"children":"404: This page could not be found."}],["$","div",null,{"style":{"fontFamily":"system-ui,\"Segoe UI\",Roboto,Helvetica,Arial,sans-serif,\"Apple Color Emoji\",\"Segoe UI Emoji\"","height":"100vh","textAlign":"center","display":"flex","flexDirection":"column","alignItems":"center","justifyContent":"center"},"children":["$","div",null,{"children":[["$","style",null,{"dangerouslySetInnerHTML":{"__html":"body{color:#000;background:#fff;margin:0}.next-error-h1{border-right:1px solid rgba(0,0,0,.3)}@media (prefers-color-scheme:dark){body{color:#fff;background:#000}.next-error-h1{border-right:1px solid rgba(255,255,255,.3)}}"}}],["$","h1",null,{"className":"next-error-h1","style":{"display":"inline-block","margin":"0 20px 0 0","padding":"0 23px 0 0","fontSize":24,"fontWeight":500,"verticalAlign":"top","lineHeight":"49px"},"children":"404"}],["$","div",null,{"style":{"display":"inline-block"},"children":["$","h2",null,{"style":{"fontSize":14,"fontWeight":400,"lineHeight":"49px","margin":0},"children":"This page could not be found."}]}]]}]}]],"notFoundStyles":[],"styles":null}]}]}],null]],[[["$","link","0",{"rel":"stylesheet","href":"/ui/_next/static/css/173c5a76ba57a3b8.css","precedence":"next","crossOrigin":""}]],"$L6"]]]]
|
||||
6:[["$","meta","0",{"name":"viewport","content":"width=device-width, initial-scale=1"}],["$","meta","1",{"charSet":"utf-8"}],["$","title","2",{"children":"🚅 LiteLLM"}],["$","meta","3",{"name":"description","content":"LiteLLM Proxy Admin UI"}],["$","link","4",{"rel":"icon","href":"/ui/favicon.ico","type":"image/x-icon","sizes":"16x16"}],["$","meta","5",{"name":"next-size-adjust"}]]
|
||||
1:null
|
||||
|
|
|
|||
|
|
@ -125,7 +125,7 @@ class _PROXY_MaxParallelRequestsHandler(CustomLogger):
|
|||
# ------------
|
||||
|
||||
new_val = {
|
||||
"current_requests": current["current_requests"] - 1,
|
||||
"current_requests": max(current["current_requests"] - 1, 0),
|
||||
"current_tpm": current["current_tpm"] + total_tokens,
|
||||
"current_rpm": current["current_rpm"] + 1,
|
||||
}
|
||||
|
|
@ -183,7 +183,7 @@ class _PROXY_MaxParallelRequestsHandler(CustomLogger):
|
|||
}
|
||||
|
||||
new_val = {
|
||||
"current_requests": current["current_requests"] - 1,
|
||||
"current_requests": max(current["current_requests"] - 1, 0),
|
||||
"current_tpm": current["current_tpm"],
|
||||
"current_rpm": current["current_rpm"],
|
||||
}
|
||||
|
|
|
|||
|
|
@ -424,14 +424,25 @@ def run_server(
|
|||
if database_url is not None and isinstance(database_url, str):
|
||||
os.environ["DATABASE_URL"] = database_url
|
||||
|
||||
if os.getenv("DATABASE_URL", None) is not None:
|
||||
if (
|
||||
os.getenv("DATABASE_URL", None) is not None
|
||||
or os.getenv("DIRECT_URL", None) is not None
|
||||
):
|
||||
try:
|
||||
### add connection pool + pool timeout args
|
||||
params = {"connection_limit": 500, "pool_timeout": 60}
|
||||
database_url = os.getenv("DATABASE_URL")
|
||||
modified_url = append_query_params(database_url, params)
|
||||
os.environ["DATABASE_URL"] = modified_url
|
||||
###
|
||||
if os.getenv("DATABASE_URL", None) is not None:
|
||||
### add connection pool + pool timeout args
|
||||
params = {"connection_limit": 100, "pool_timeout": 60}
|
||||
database_url = os.getenv("DATABASE_URL")
|
||||
modified_url = append_query_params(database_url, params)
|
||||
os.environ["DATABASE_URL"] = modified_url
|
||||
###
|
||||
if os.getenv("DIRECT_URL", None) is not None:
|
||||
### add connection pool + pool timeout args
|
||||
params = {"connection_limit": 100, "pool_timeout": 60}
|
||||
database_url = os.getenv("DIRECT_URL")
|
||||
modified_url = append_query_params(database_url, params)
|
||||
os.environ["DIRECT_URL"] = modified_url
|
||||
###
|
||||
subprocess.run(["prisma"], capture_output=True)
|
||||
is_prisma_runnable = True
|
||||
except FileNotFoundError:
|
||||
|
|
|
|||
|
|
@ -7,10 +7,8 @@ model_list:
|
|||
api_version: "2023-07-01-preview"
|
||||
model_info:
|
||||
mode: chat
|
||||
input_cost_per_token: 0.0.00006
|
||||
output_cost_per_token: 0.00003
|
||||
max_tokens: 4096
|
||||
base_model: gpt-3.5-turbo
|
||||
base_model: azure/gpt-4-1106-preview
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: azure/chatgpt-v-2
|
||||
|
|
@ -74,11 +72,6 @@ litellm_settings:
|
|||
max_budget: 1.5000
|
||||
models: ["azure-gpt-3.5"]
|
||||
duration: None
|
||||
cache: True # set cache responses to True
|
||||
cache_params:
|
||||
type: "redis-semantic"
|
||||
similarity_threshold: 0.8
|
||||
redis_semantic_cache_embedding_model: azure-embedding-model
|
||||
upperbound_key_generate_params:
|
||||
max_budget: 100
|
||||
duration: "30d"
|
||||
|
|
|
|||
|
|
@ -809,16 +809,15 @@ async def _PROXY_track_cost_callback(
|
|||
litellm_params = kwargs.get("litellm_params", {}) or {}
|
||||
proxy_server_request = litellm_params.get("proxy_server_request") or {}
|
||||
user_id = proxy_server_request.get("body", {}).get("user", None)
|
||||
user_id = user_id or kwargs["litellm_params"]["metadata"].get(
|
||||
"user_api_key_user_id", None
|
||||
)
|
||||
if kwargs.get("response_cost", None) is not None:
|
||||
response_cost = kwargs["response_cost"]
|
||||
user_api_key = kwargs["litellm_params"]["metadata"].get(
|
||||
"user_api_key", None
|
||||
)
|
||||
|
||||
user_id = user_id or kwargs["litellm_params"]["metadata"].get(
|
||||
"user_api_key_user_id", None
|
||||
)
|
||||
|
||||
if kwargs.get("cache_hit", False) == True:
|
||||
response_cost = 0.0
|
||||
verbose_proxy_logger.info(
|
||||
|
|
@ -852,9 +851,21 @@ async def _PROXY_track_cost_callback(
|
|||
f"Model not in litellm model cost map. Add custom pricing - https://docs.litellm.ai/docs/proxy/custom_pricing"
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.debug(
|
||||
f"error in tracking cost callback - {traceback.format_exc}"
|
||||
error_msg = f"error in tracking cost callback - {traceback.format_exc()}"
|
||||
model = kwargs.get("model", "")
|
||||
metadata = kwargs.get("litellm_params", {}).get("metadata", {})
|
||||
error_msg += f"\n Args to _PROXY_track_cost_callback\n model: {model}\n metadata: {metadata}\n"
|
||||
user_id = user_id or "not-found"
|
||||
asyncio.create_task(
|
||||
proxy_logging_obj.budget_alerts(
|
||||
user_max_budget=0,
|
||||
user_current_spend=0,
|
||||
type="failed_tracking",
|
||||
user_info=user_id,
|
||||
error_message=error_msg,
|
||||
)
|
||||
)
|
||||
verbose_proxy_logger.debug(f"error in tracking cost callback - {error_msg}")
|
||||
|
||||
|
||||
async def update_database(
|
||||
|
|
@ -2004,12 +2015,15 @@ async def startup_event():
|
|||
)
|
||||
|
||||
### START BUDGET SCHEDULER ###
|
||||
scheduler = AsyncIOScheduler()
|
||||
interval = random.randint(
|
||||
597, 605
|
||||
) # random interval, so multiple workers avoid resetting budget at the same time
|
||||
scheduler.add_job(reset_budget, "interval", seconds=interval, args=[prisma_client])
|
||||
scheduler.start()
|
||||
if prisma_client is not None:
|
||||
scheduler = AsyncIOScheduler()
|
||||
interval = random.randint(
|
||||
597, 605
|
||||
) # random interval, so multiple workers avoid resetting budget at the same time
|
||||
scheduler.add_job(
|
||||
reset_budget, "interval", seconds=interval, args=[prisma_client]
|
||||
)
|
||||
scheduler.start()
|
||||
|
||||
|
||||
#### API ENDPOINTS ####
|
||||
|
|
@ -3001,7 +3015,16 @@ async def info_key_fn(
|
|||
tags=["budget & spend Tracking"],
|
||||
dependencies=[Depends(user_api_key_auth)],
|
||||
)
|
||||
async def spend_key_fn():
|
||||
async def spend_key_fn(
|
||||
start_date: Optional[str] = fastapi.Query(
|
||||
default=None,
|
||||
description="Time from which to start viewing key spend",
|
||||
),
|
||||
end_date: Optional[str] = fastapi.Query(
|
||||
default=None,
|
||||
description="Time till which to view key spend",
|
||||
),
|
||||
):
|
||||
"""
|
||||
View all keys created, ordered by spend
|
||||
|
||||
|
|
@ -3018,9 +3041,41 @@ async def spend_key_fn():
|
|||
f"Database not connected. Connect a database to your proxy - https://docs.litellm.ai/docs/simple_proxy#managing-auth---virtual-keys"
|
||||
)
|
||||
|
||||
key_info = await prisma_client.get_data(table_name="key", query_type="find_all")
|
||||
if (
|
||||
start_date is not None
|
||||
and isinstance(start_date, str)
|
||||
and end_date is not None
|
||||
and isinstance(end_date, str)
|
||||
):
|
||||
# Convert the date strings to datetime objects
|
||||
start_date_obj = datetime.strptime(start_date, "%Y-%m-%d")
|
||||
end_date_obj = datetime.strptime(end_date, "%Y-%m-%d")
|
||||
|
||||
return key_info
|
||||
# SQL query
|
||||
response = await prisma_client.db.litellm_spendlogs.group_by(
|
||||
by=["api_key", "startTime"],
|
||||
where={
|
||||
"startTime": {
|
||||
"gte": start_date_obj, # Greater than or equal to Start Date
|
||||
"lte": end_date_obj, # Less than or equal to End Date
|
||||
}
|
||||
},
|
||||
sum={
|
||||
"spend": True,
|
||||
},
|
||||
)
|
||||
|
||||
# TODO: Execute SQL query and return the results
|
||||
|
||||
return {
|
||||
"message": "This is your SQL query",
|
||||
"response": response,
|
||||
}
|
||||
else:
|
||||
key_info = await prisma_client.get_data(
|
||||
table_name="key", query_type="find_all"
|
||||
)
|
||||
return key_info
|
||||
|
||||
except Exception as e:
|
||||
raise HTTPException(
|
||||
|
|
@ -3441,10 +3496,25 @@ async def login(request: Request):
|
|||
|
||||
litellm_dashboard_ui = "/ui/"
|
||||
|
||||
user_role = "app_owner"
|
||||
if (
|
||||
os.getenv("PROXY_ADMIN_ID", None) is not None
|
||||
and os.environ["PROXY_ADMIN_ID"] == user_id
|
||||
):
|
||||
# checks if user is admin
|
||||
user_role = "app_admin"
|
||||
|
||||
import jwt
|
||||
|
||||
jwt_token = jwt.encode(
|
||||
{"user_id": user_id, "key": key}, "secret", algorithm="HS256"
|
||||
{
|
||||
"user_id": user_id,
|
||||
"key": key,
|
||||
"user_email": user_id,
|
||||
"user_role": user_role,
|
||||
},
|
||||
"secret",
|
||||
algorithm="HS256",
|
||||
)
|
||||
litellm_dashboard_ui += "?userID=" + user_id + "&token=" + jwt_token
|
||||
|
||||
|
|
|
|||
|
|
@ -1,6 +1,7 @@
|
|||
datasource client {
|
||||
provider = "postgresql"
|
||||
url = env("DATABASE_URL")
|
||||
directUrl = env("DIRECT_URL")
|
||||
}
|
||||
|
||||
generator client {
|
||||
|
|
|
|||
|
|
@ -198,10 +198,17 @@ class ProxyLogging:
|
|||
|
||||
async def budget_alerts(
|
||||
self,
|
||||
type: Literal["token_budget", "user_budget", "user_and_proxy_budget"],
|
||||
type: Literal[
|
||||
"token_budget",
|
||||
"user_budget",
|
||||
"user_and_proxy_budget",
|
||||
"failed_budgets",
|
||||
"failed_tracking",
|
||||
],
|
||||
user_max_budget: float,
|
||||
user_current_spend: float,
|
||||
user_info=None,
|
||||
error_message="",
|
||||
):
|
||||
if self.alerting is None:
|
||||
# do nothing if alerting is not switched on
|
||||
|
|
@ -221,6 +228,15 @@ class ProxyLogging:
|
|||
max_budget = token_info["max_budget"]
|
||||
user_id = token_info["user_id"]
|
||||
user_info = f"""\nToken: {token}\nSpend: ${spend}\nMax Budget: ${max_budget}\nUser ID: {user_id}"""
|
||||
elif type == "failed_tracking":
|
||||
user_id = str(user_info)
|
||||
user_info = f"\nUser ID: {user_id}\n Error {error_message}"
|
||||
message = "Failed Tracking Cost for" + user_info
|
||||
await self.alerting_handler(
|
||||
message=message,
|
||||
level="High",
|
||||
)
|
||||
return
|
||||
else:
|
||||
user_info = str(user_info)
|
||||
# percent of max_budget left to spend
|
||||
|
|
|
|||
|
|
@ -304,7 +304,10 @@ class Router:
|
|||
specific_deployment=kwargs.pop("specific_deployment", None),
|
||||
)
|
||||
kwargs.setdefault("metadata", {}).update(
|
||||
{"deployment": deployment["litellm_params"]["model"]}
|
||||
{
|
||||
"deployment": deployment["litellm_params"]["model"],
|
||||
"model_info": deployment.get("model_info", {}),
|
||||
}
|
||||
)
|
||||
data = deployment["litellm_params"].copy()
|
||||
kwargs["model_info"] = deployment.get("model_info", {})
|
||||
|
|
@ -376,7 +379,10 @@ class Router:
|
|||
specific_deployment=kwargs.pop("specific_deployment", None),
|
||||
)
|
||||
kwargs.setdefault("metadata", {}).update(
|
||||
{"deployment": deployment["litellm_params"]["model"]}
|
||||
{
|
||||
"deployment": deployment["litellm_params"]["model"],
|
||||
"model_info": deployment.get("model_info", {}),
|
||||
}
|
||||
)
|
||||
kwargs["model_info"] = deployment.get("model_info", {})
|
||||
data = deployment["litellm_params"].copy()
|
||||
|
|
@ -451,7 +457,10 @@ class Router:
|
|||
specific_deployment=kwargs.pop("specific_deployment", None),
|
||||
)
|
||||
kwargs.setdefault("metadata", {}).update(
|
||||
{"deployment": deployment["litellm_params"]["model"]}
|
||||
{
|
||||
"deployment": deployment["litellm_params"]["model"],
|
||||
"model_info": deployment.get("model_info", {}),
|
||||
}
|
||||
)
|
||||
kwargs["model_info"] = deployment.get("model_info", {})
|
||||
data = deployment["litellm_params"].copy()
|
||||
|
|
@ -526,7 +535,10 @@ class Router:
|
|||
specific_deployment=kwargs.pop("specific_deployment", None),
|
||||
)
|
||||
kwargs.setdefault("metadata", {}).update(
|
||||
{"deployment": deployment["litellm_params"]["model"]}
|
||||
{
|
||||
"deployment": deployment["litellm_params"]["model"],
|
||||
"model_info": deployment.get("model_info", {}),
|
||||
}
|
||||
)
|
||||
kwargs["model_info"] = deployment.get("model_info", {})
|
||||
data = deployment["litellm_params"].copy()
|
||||
|
|
@ -654,7 +666,10 @@ class Router:
|
|||
specific_deployment=kwargs.pop("specific_deployment", None),
|
||||
)
|
||||
kwargs.setdefault("metadata", {}).update(
|
||||
{"deployment": deployment["litellm_params"]["model"]}
|
||||
{
|
||||
"deployment": deployment["litellm_params"]["model"],
|
||||
"model_info": deployment.get("model_info", {}),
|
||||
}
|
||||
)
|
||||
kwargs["model_info"] = deployment.get("model_info", {})
|
||||
data = deployment["litellm_params"].copy()
|
||||
|
|
@ -780,7 +795,10 @@ class Router:
|
|||
specific_deployment=kwargs.pop("specific_deployment", None),
|
||||
)
|
||||
kwargs.setdefault("metadata", {}).update(
|
||||
{"deployment": deployment["litellm_params"]["model"]}
|
||||
{
|
||||
"deployment": deployment["litellm_params"]["model"],
|
||||
"model_info": deployment.get("model_info", {}),
|
||||
}
|
||||
)
|
||||
kwargs["model_info"] = deployment.get("model_info", {})
|
||||
data = deployment["litellm_params"].copy()
|
||||
|
|
@ -1407,7 +1425,6 @@ class Router:
|
|||
max_retries = litellm.get_secret(max_retries_env_name)
|
||||
litellm_params["max_retries"] = max_retries
|
||||
|
||||
|
||||
# proxy support
|
||||
import os
|
||||
import httpx
|
||||
|
|
|
|||
|
|
@ -66,6 +66,7 @@ def test_s3_logging():
|
|||
response = asyncio.run(_test())
|
||||
expected_keys.append(response.id)
|
||||
print(f"response: {response}")
|
||||
time.sleep(5) # wait 5s for logs to land
|
||||
|
||||
import boto3
|
||||
|
||||
|
|
@ -121,6 +122,71 @@ def test_s3_logging():
|
|||
# test_s3_logging()
|
||||
|
||||
|
||||
def test_s3_logging_async():
|
||||
# this tests time added to make s3 logging calls, vs just acompletion calls
|
||||
try:
|
||||
litellm.set_verbose = True
|
||||
# Make 5 calls with an empty success_callback
|
||||
litellm.success_callback = []
|
||||
start_time_empty_callback = asyncio.run(make_async_calls())
|
||||
print("done with no callback test")
|
||||
|
||||
print("starting s3 logging load test")
|
||||
# Make 5 calls with success_callback set to "langfuse"
|
||||
litellm.success_callback = ["s3"]
|
||||
litellm.s3_callback_params = {
|
||||
"s3_bucket_name": "litellm-logs",
|
||||
"s3_aws_secret_access_key": "os.environ/AWS_SECRET_ACCESS_KEY",
|
||||
"s3_aws_access_key_id": "os.environ/AWS_ACCESS_KEY_ID",
|
||||
}
|
||||
start_time_s3 = asyncio.run(make_async_calls())
|
||||
print("done with s3 test")
|
||||
|
||||
# Compare the time for both scenarios
|
||||
print(f"Time taken with success_callback='s3': {start_time_s3}")
|
||||
print(f"Time taken with empty success_callback: {start_time_empty_callback}")
|
||||
|
||||
# assert the diff is not more than 1 second
|
||||
assert abs(start_time_s3 - start_time_empty_callback) < 1
|
||||
|
||||
except litellm.Timeout as e:
|
||||
pass
|
||||
except Exception as e:
|
||||
pytest.fail(f"An exception occurred - {e}")
|
||||
|
||||
|
||||
async def make_async_calls():
|
||||
tasks = []
|
||||
for _ in range(5):
|
||||
task = asyncio.create_task(
|
||||
litellm.acompletion(
|
||||
model="azure/chatgpt-v-2",
|
||||
messages=[{"role": "user", "content": "This is a test"}],
|
||||
max_tokens=5,
|
||||
temperature=0.7,
|
||||
timeout=5,
|
||||
user="langfuse_latency_test_user",
|
||||
mock_response="It's simple to use and easy to get started",
|
||||
)
|
||||
)
|
||||
tasks.append(task)
|
||||
|
||||
# Measure the start time before running the tasks
|
||||
start_time = asyncio.get_event_loop().time()
|
||||
|
||||
# Wait for all tasks to complete
|
||||
responses = await asyncio.gather(*tasks)
|
||||
|
||||
# Print the responses when tasks return
|
||||
for idx, response in enumerate(responses):
|
||||
print(f"Response from Task {idx + 1}: {response}")
|
||||
|
||||
# Calculate the total time taken
|
||||
total_time = asyncio.get_event_loop().time() - start_time
|
||||
|
||||
return total_time
|
||||
|
||||
|
||||
def test_s3_logging_r2():
|
||||
# all s3 requests need to be in one test function
|
||||
# since we are modifying stdout, and pytests runs tests in parallel
|
||||
|
|
|
|||
|
|
@ -696,6 +696,58 @@ def test_s3_cache_acompletion_stream_azure():
|
|||
# test_s3_cache_acompletion_stream_azure()
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_s3_cache_acompletion_azure():
|
||||
import asyncio
|
||||
import logging
|
||||
import tracemalloc
|
||||
|
||||
tracemalloc.start()
|
||||
logging.basicConfig(level=logging.DEBUG)
|
||||
|
||||
try:
|
||||
litellm.set_verbose = True
|
||||
random_word = generate_random_word()
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": f"write a one sentence poem about: {random_word}",
|
||||
}
|
||||
]
|
||||
litellm.cache = Cache(
|
||||
type="s3", s3_bucket_name="cache-bucket-litellm", s3_region_name="us-west-2"
|
||||
)
|
||||
print("s3 Cache: test for caching, streaming + completion")
|
||||
|
||||
response1 = await litellm.acompletion(
|
||||
model="azure/chatgpt-v-2",
|
||||
messages=messages,
|
||||
max_tokens=40,
|
||||
temperature=1,
|
||||
)
|
||||
print(response1)
|
||||
|
||||
time.sleep(2)
|
||||
|
||||
response2 = await litellm.acompletion(
|
||||
model="azure/chatgpt-v-2",
|
||||
messages=messages,
|
||||
max_tokens=40,
|
||||
temperature=1,
|
||||
)
|
||||
|
||||
print(response2)
|
||||
|
||||
assert response1.id == response2.id
|
||||
|
||||
litellm.cache = None
|
||||
litellm.success_callback = []
|
||||
litellm._async_success_callback = []
|
||||
except Exception as e:
|
||||
print(e)
|
||||
raise e
|
||||
|
||||
|
||||
# test_redis_cache_acompletion_stream_bedrock()
|
||||
# redis cache with custom keys
|
||||
def custom_get_cache_key(*args, **kwargs):
|
||||
|
|
|
|||
|
|
@ -110,6 +110,32 @@ def test_completion_mistral_api():
|
|||
# test_completion_mistral_api()
|
||||
|
||||
|
||||
def test_completion_mistral_api_modified_input():
|
||||
try:
|
||||
litellm.set_verbose = True
|
||||
response = completion(
|
||||
model="mistral/mistral-tiny",
|
||||
max_tokens=5,
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": [{"type": "text", "text": "Hey, how's it going?"}],
|
||||
}
|
||||
],
|
||||
)
|
||||
# Add any assertions here to check the response
|
||||
print(response)
|
||||
|
||||
cost = litellm.completion_cost(completion_response=response)
|
||||
print("cost to make mistral completion=", cost)
|
||||
assert cost > 0.0
|
||||
except Exception as e:
|
||||
if "500" in str(e):
|
||||
pass
|
||||
else:
|
||||
pytest.fail(f"Error occurred: {e}")
|
||||
|
||||
|
||||
def test_completion_claude2_1():
|
||||
try:
|
||||
print("claude2.1 test request")
|
||||
|
|
@ -1495,6 +1521,33 @@ def test_completion_chat_sagemaker_mistral():
|
|||
|
||||
|
||||
# test_completion_chat_sagemaker_mistral()
|
||||
|
||||
|
||||
def test_completion_bedrock_titan_null_response():
|
||||
try:
|
||||
response = completion(
|
||||
model="bedrock/amazon.titan-text-lite-v1",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Hello!",
|
||||
},
|
||||
{
|
||||
"role": "assistant",
|
||||
"content": "Hello! How can I help you?",
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What model are you?",
|
||||
},
|
||||
],
|
||||
)
|
||||
# Add any assertions here to check the response
|
||||
pytest.fail(f"Expected to fail")
|
||||
except Exception as e:
|
||||
pass
|
||||
|
||||
|
||||
def test_completion_bedrock_titan():
|
||||
try:
|
||||
response = completion(
|
||||
|
|
@ -1743,7 +1796,7 @@ def test_azure_cloudflare_api():
|
|||
|
||||
def test_completion_anyscale_2():
|
||||
try:
|
||||
# litellm.set_verbose=True
|
||||
# litellm.set_verbose = True
|
||||
messages = [
|
||||
{"role": "system", "content": "You're a good bot"},
|
||||
{
|
||||
|
|
|
|||
|
|
@ -256,6 +256,7 @@ class CompletionCustomHandler(
|
|||
async def async_log_success_event(self, kwargs, response_obj, start_time, end_time):
|
||||
try:
|
||||
self.states.append("async_success")
|
||||
print("in async success, kwargs: ", kwargs)
|
||||
## START TIME
|
||||
assert isinstance(start_time, datetime)
|
||||
## END TIME
|
||||
|
|
@ -266,6 +267,38 @@ class CompletionCustomHandler(
|
|||
)
|
||||
## KWARGS
|
||||
assert isinstance(kwargs["model"], str)
|
||||
|
||||
# checking we use base_model for azure cost calculation
|
||||
base_model = litellm.utils._get_base_model_from_metadata(
|
||||
model_call_details=kwargs
|
||||
)
|
||||
|
||||
if (
|
||||
kwargs["model"] == "chatgpt-v-2"
|
||||
and base_model is not None
|
||||
and kwargs["stream"] != True
|
||||
):
|
||||
# when base_model is set for azure, we should use pricing for the base_model
|
||||
# this checks response_cost == litellm.cost_per_token(model=base_model)
|
||||
assert isinstance(kwargs["response_cost"], float)
|
||||
response_cost = kwargs["response_cost"]
|
||||
print(
|
||||
f"response_cost: {response_cost}, for model: {kwargs['model']} and base_model: {base_model}"
|
||||
)
|
||||
prompt_tokens = response_obj.usage.prompt_tokens
|
||||
completion_tokens = response_obj.usage.completion_tokens
|
||||
# ensure the pricing is based on the base_model here
|
||||
prompt_price, completion_price = litellm.cost_per_token(
|
||||
model=base_model,
|
||||
prompt_tokens=prompt_tokens,
|
||||
completion_tokens=completion_tokens,
|
||||
)
|
||||
expected_price = prompt_price + completion_price
|
||||
print(f"expected price: {expected_price}")
|
||||
assert (
|
||||
response_cost == expected_price
|
||||
), f"response_cost: {response_cost} != expected_price: {expected_price}. For model: {kwargs['model']} and base_model: {base_model}. should have used base_model for price"
|
||||
|
||||
assert isinstance(kwargs["messages"], list)
|
||||
assert isinstance(kwargs["optional_params"], dict)
|
||||
assert isinstance(kwargs["litellm_params"], dict)
|
||||
|
|
@ -345,6 +378,7 @@ async def test_async_chat_azure():
|
|||
customHandler_streaming_azure_router = CompletionCustomHandler()
|
||||
customHandler_failure = CompletionCustomHandler()
|
||||
litellm.callbacks = [customHandler_completion_azure_router]
|
||||
litellm.set_verbose = True
|
||||
model_list = [
|
||||
{
|
||||
"model_name": "gpt-3.5-turbo", # openai model name
|
||||
|
|
@ -354,6 +388,7 @@ async def test_async_chat_azure():
|
|||
"api_version": os.getenv("AZURE_API_VERSION"),
|
||||
"api_base": os.getenv("AZURE_API_BASE"),
|
||||
},
|
||||
"model_info": {"base_model": "azure/gpt-4-1106-preview"},
|
||||
"tpm": 240000,
|
||||
"rpm": 1800,
|
||||
},
|
||||
|
|
|
|||
94
litellm/tests/test_load_test_router_s3.py
Normal file
94
litellm/tests/test_load_test_router_s3.py
Normal file
|
|
@ -0,0 +1,94 @@
|
|||
# import sys, os
|
||||
# import traceback
|
||||
# from dotenv import load_dotenv
|
||||
# import copy
|
||||
|
||||
# load_dotenv()
|
||||
# sys.path.insert(
|
||||
# 0, os.path.abspath("../..")
|
||||
# ) # Adds the parent directory to the system path
|
||||
# import asyncio
|
||||
# from litellm import Router, Timeout
|
||||
# import time
|
||||
# from litellm.caching import Cache
|
||||
# import litellm
|
||||
|
||||
# litellm.cache = Cache(
|
||||
# type="s3", s3_bucket_name="cache-bucket-litellm", s3_region_name="us-west-2"
|
||||
# )
|
||||
|
||||
# ### Test calling router with s3 Cache
|
||||
|
||||
|
||||
# async def call_acompletion(semaphore, router: Router, input_data):
|
||||
# async with semaphore:
|
||||
# try:
|
||||
# # Use asyncio.wait_for to set a timeout for the task
|
||||
# response = await router.acompletion(**input_data)
|
||||
# # Handle the response as needed
|
||||
# print(response)
|
||||
# return response
|
||||
# except Timeout:
|
||||
# print(f"Task timed out: {input_data}")
|
||||
# return None # You may choose to return something else or raise an exception
|
||||
|
||||
|
||||
# async def main():
|
||||
# # Initialize the Router
|
||||
# model_list = [
|
||||
# {
|
||||
# "model_name": "gpt-3.5-turbo",
|
||||
# "litellm_params": {
|
||||
# "model": "gpt-3.5-turbo",
|
||||
# "api_key": os.getenv("OPENAI_API_KEY"),
|
||||
# },
|
||||
# },
|
||||
# {
|
||||
# "model_name": "gpt-3.5-turbo",
|
||||
# "litellm_params": {
|
||||
# "model": "azure/chatgpt-v-2",
|
||||
# "api_key": os.getenv("AZURE_API_KEY"),
|
||||
# "api_base": os.getenv("AZURE_API_BASE"),
|
||||
# "api_version": os.getenv("AZURE_API_VERSION"),
|
||||
# },
|
||||
# },
|
||||
# ]
|
||||
# router = Router(model_list=model_list, num_retries=3, timeout=10)
|
||||
|
||||
# # Create a semaphore with a capacity of 100
|
||||
# semaphore = asyncio.Semaphore(100)
|
||||
|
||||
# # List to hold all task references
|
||||
# tasks = []
|
||||
# start_time_all_tasks = time.time()
|
||||
# # Launch 1000 tasks
|
||||
# for _ in range(500):
|
||||
# task = asyncio.create_task(
|
||||
# call_acompletion(
|
||||
# semaphore,
|
||||
# router,
|
||||
# {
|
||||
# "model": "gpt-3.5-turbo",
|
||||
# "messages": [{"role": "user", "content": "Hey, how's it going?"}],
|
||||
# },
|
||||
# )
|
||||
# )
|
||||
# tasks.append(task)
|
||||
|
||||
# # Wait for all tasks to complete
|
||||
# responses = await asyncio.gather(*tasks)
|
||||
# # Process responses as needed
|
||||
# # Record the end time for all tasks
|
||||
# end_time_all_tasks = time.time()
|
||||
# # Calculate the total time for all tasks
|
||||
# total_time_all_tasks = end_time_all_tasks - start_time_all_tasks
|
||||
# print(f"Total time for all tasks: {total_time_all_tasks} seconds")
|
||||
|
||||
# # Calculate the average time per response
|
||||
# average_time_per_response = total_time_all_tasks / len(responses)
|
||||
# print(f"Average time per response: {average_time_per_response} seconds")
|
||||
# print(f"NUMBER OF COMPLETED TASKS: {len(responses)}")
|
||||
|
||||
|
||||
# # Run the main function
|
||||
# asyncio.run(main())
|
||||
|
|
@ -9,6 +9,7 @@
|
|||
# ) # Adds the parent directory to the system path
|
||||
# import asyncio
|
||||
# from litellm import Router, Timeout
|
||||
# import time
|
||||
|
||||
|
||||
# async def call_acompletion(semaphore, router: Router, input_data):
|
||||
|
|
@ -17,6 +18,7 @@
|
|||
# # Use asyncio.wait_for to set a timeout for the task
|
||||
# response = await router.acompletion(**input_data)
|
||||
# # Handle the response as needed
|
||||
# print(response)
|
||||
# return response
|
||||
# except Timeout:
|
||||
# print(f"Task timed out: {input_data}")
|
||||
|
|
@ -42,15 +44,6 @@
|
|||
# "api_version": os.getenv("AZURE_API_VERSION"),
|
||||
# },
|
||||
# },
|
||||
# {
|
||||
# "model_name": "gpt-3.5-turbo",
|
||||
# "litellm_params": {
|
||||
# "model": "azure/chatgpt-functioncalling",
|
||||
# "api_key": os.getenv("AZURE_API_KEY"),
|
||||
# "api_base": os.getenv("AZURE_API_BASE"),
|
||||
# "api_version": os.getenv("AZURE_API_VERSION"),
|
||||
# },
|
||||
# },
|
||||
# ]
|
||||
# router = Router(model_list=model_list, num_retries=3, timeout=10)
|
||||
|
||||
|
|
@ -59,9 +52,9 @@
|
|||
|
||||
# # List to hold all task references
|
||||
# tasks = []
|
||||
|
||||
# start_time_all_tasks = time.time()
|
||||
# # Launch 1000 tasks
|
||||
# for _ in range(1000):
|
||||
# for _ in range(500):
|
||||
# task = asyncio.create_task(
|
||||
# call_acompletion(
|
||||
# semaphore,
|
||||
|
|
@ -77,6 +70,15 @@
|
|||
# # Wait for all tasks to complete
|
||||
# responses = await asyncio.gather(*tasks)
|
||||
# # Process responses as needed
|
||||
# # Record the end time for all tasks
|
||||
# end_time_all_tasks = time.time()
|
||||
# # Calculate the total time for all tasks
|
||||
# total_time_all_tasks = end_time_all_tasks - start_time_all_tasks
|
||||
# print(f"Total time for all tasks: {total_time_all_tasks} seconds")
|
||||
|
||||
# # Calculate the average time per response
|
||||
# average_time_per_response = total_time_all_tasks / len(responses)
|
||||
# print(f"Average time per response: {average_time_per_response} seconds")
|
||||
# print(f"NUMBER OF COMPLETED TASKS: {len(responses)}")
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -292,6 +292,7 @@ async def test_normal_router_call():
|
|||
model="azure-model",
|
||||
messages=[{"role": "user", "content": "Hey, how's it going?"}],
|
||||
metadata={"user_api_key": _api_key},
|
||||
mock_response="hello",
|
||||
)
|
||||
await asyncio.sleep(1) # success is done in a separate thread
|
||||
print(f"response: {response}")
|
||||
|
|
@ -450,6 +451,7 @@ async def test_streaming_router_call():
|
|||
messages=[{"role": "user", "content": "Hey, how's it going?"}],
|
||||
stream=True,
|
||||
metadata={"user_api_key": _api_key},
|
||||
mock_response="hello",
|
||||
)
|
||||
async for chunk in response:
|
||||
continue
|
||||
|
|
@ -526,6 +528,7 @@ async def test_streaming_router_tpm_limit():
|
|||
messages=[{"role": "user", "content": "Write me a paragraph on the moon"}],
|
||||
stream=True,
|
||||
metadata={"user_api_key": _api_key},
|
||||
mock_response="hello",
|
||||
)
|
||||
async for chunk in response:
|
||||
continue
|
||||
|
|
|
|||
124
litellm/utils.py
124
litellm/utils.py
|
|
@ -1079,10 +1079,17 @@ class Logging:
|
|||
call_type=self.call_type,
|
||||
)
|
||||
else:
|
||||
# check if base_model set on azure
|
||||
base_model = _get_base_model_from_metadata(
|
||||
model_call_details=self.model_call_details
|
||||
)
|
||||
# base_model defaults to None if not set on model_info
|
||||
self.model_call_details[
|
||||
"response_cost"
|
||||
] = litellm.completion_cost(
|
||||
completion_response=result, call_type=self.call_type
|
||||
completion_response=result,
|
||||
call_type=self.call_type,
|
||||
model=base_model,
|
||||
)
|
||||
verbose_logger.debug(
|
||||
f"Model={self.model}; cost={self.model_call_details['response_cost']}"
|
||||
|
|
@ -1158,10 +1165,16 @@ class Logging:
|
|||
if self.model_call_details.get("cache_hit", False) == True:
|
||||
self.model_call_details["response_cost"] = 0.0
|
||||
else:
|
||||
# check if base_model set on azure
|
||||
base_model = _get_base_model_from_metadata(
|
||||
model_call_details=self.model_call_details
|
||||
)
|
||||
# base_model defaults to None if not set on model_info
|
||||
self.model_call_details[
|
||||
"response_cost"
|
||||
] = litellm.completion_cost(
|
||||
completion_response=complete_streaming_response,
|
||||
model=base_model,
|
||||
)
|
||||
verbose_logger.debug(
|
||||
f"Model={self.model}; cost={self.model_call_details['response_cost']}"
|
||||
|
|
@ -1369,6 +1382,36 @@ class Logging:
|
|||
end_time=end_time,
|
||||
print_verbose=print_verbose,
|
||||
)
|
||||
if callback == "s3":
|
||||
global s3Logger
|
||||
if s3Logger is None:
|
||||
s3Logger = S3Logger()
|
||||
if self.stream:
|
||||
if "complete_streaming_response" in self.model_call_details:
|
||||
print_verbose(
|
||||
"S3Logger Logger: Got Stream Event - Completed Stream Response"
|
||||
)
|
||||
s3Logger.log_event(
|
||||
kwargs=self.model_call_details,
|
||||
response_obj=self.model_call_details[
|
||||
"complete_streaming_response"
|
||||
],
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
print_verbose=print_verbose,
|
||||
)
|
||||
else:
|
||||
print_verbose(
|
||||
"S3Logger Logger: Got Stream Event - No complete stream response as yet"
|
||||
)
|
||||
else:
|
||||
s3Logger.log_event(
|
||||
kwargs=self.model_call_details,
|
||||
response_obj=result,
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
print_verbose=print_verbose,
|
||||
)
|
||||
if (
|
||||
isinstance(callback, CustomLogger)
|
||||
and self.model_call_details.get("litellm_params", {}).get(
|
||||
|
|
@ -1479,8 +1522,14 @@ class Logging:
|
|||
if self.model_call_details.get("cache_hit", False) == True:
|
||||
self.model_call_details["response_cost"] = 0.0
|
||||
else:
|
||||
# check if base_model set on azure
|
||||
base_model = _get_base_model_from_metadata(
|
||||
model_call_details=self.model_call_details
|
||||
)
|
||||
# base_model defaults to None if not set on model_info
|
||||
self.model_call_details["response_cost"] = litellm.completion_cost(
|
||||
completion_response=complete_streaming_response,
|
||||
model=base_model,
|
||||
)
|
||||
verbose_logger.debug(
|
||||
f"Model={self.model}; cost={self.model_call_details['response_cost']}"
|
||||
|
|
@ -1527,7 +1576,7 @@ class Logging:
|
|||
# only add to cache once we have a complete streaming response
|
||||
litellm.cache.add_cache(result, **kwargs)
|
||||
if isinstance(callback, CustomLogger): # custom logger class
|
||||
print_verbose(f"Async success callbacks: CustomLogger")
|
||||
print_verbose(f"Async success callbacks: {callback}")
|
||||
if self.stream:
|
||||
if "complete_streaming_response" in self.model_call_details:
|
||||
await callback.async_log_success_event(
|
||||
|
|
@ -1605,36 +1654,6 @@ class Logging:
|
|||
end_time=end_time,
|
||||
print_verbose=print_verbose,
|
||||
)
|
||||
if callback == "s3":
|
||||
global s3Logger
|
||||
if s3Logger is None:
|
||||
s3Logger = S3Logger()
|
||||
if self.stream:
|
||||
if "complete_streaming_response" in self.model_call_details:
|
||||
print_verbose(
|
||||
"S3Logger Logger: Got Stream Event - Completed Stream Response"
|
||||
)
|
||||
await s3Logger._async_log_event(
|
||||
kwargs=self.model_call_details,
|
||||
response_obj=self.model_call_details[
|
||||
"complete_streaming_response"
|
||||
],
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
print_verbose=print_verbose,
|
||||
)
|
||||
else:
|
||||
print_verbose(
|
||||
"S3Logger Logger: Got Stream Event - No complete stream response as yet"
|
||||
)
|
||||
else:
|
||||
await s3Logger._async_log_event(
|
||||
kwargs=self.model_call_details,
|
||||
response_obj=result,
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
print_verbose=print_verbose,
|
||||
)
|
||||
except:
|
||||
print_verbose(
|
||||
f"LiteLLM.LoggingError: [Non-Blocking] Exception occurred while success logging {traceback.format_exc()}"
|
||||
|
|
@ -1990,11 +2009,6 @@ def client(original_function):
|
|||
# we only support async dynamo db logging for acompletion/aembedding since that's used on proxy
|
||||
litellm._async_success_callback.append(callback)
|
||||
removed_async_items.append(index)
|
||||
elif callback == "s3":
|
||||
# s3 is an async callback, it's used for the proxy and needs to be async
|
||||
# we only support async s3 logging for acompletion/aembedding since that's used on proxy
|
||||
litellm._async_success_callback.append(callback)
|
||||
removed_async_items.append(index)
|
||||
|
||||
# Pop the async items from success_callback in reverse order to avoid index issues
|
||||
for index in reversed(removed_async_items):
|
||||
|
|
@ -2767,6 +2781,12 @@ def client(original_function):
|
|||
result, *args, **kwargs
|
||||
)
|
||||
)
|
||||
elif isinstance(litellm.cache.cache, S3Cache):
|
||||
threading.Thread(
|
||||
target=litellm.cache.add_cache,
|
||||
args=(result,) + args,
|
||||
kwargs=kwargs,
|
||||
).start()
|
||||
else:
|
||||
asyncio.create_task(
|
||||
litellm.cache.async_add_cache(
|
||||
|
|
@ -4358,7 +4378,7 @@ def get_optional_params(
|
|||
if frequency_penalty is not None:
|
||||
optional_params["repeat_penalty"] = frequency_penalty
|
||||
if stop is not None:
|
||||
optional_params["stop_sequences"] = stop
|
||||
optional_params["stop"] = stop
|
||||
elif custom_llm_provider == "ollama_chat":
|
||||
supported_params = [
|
||||
"max_tokens",
|
||||
|
|
@ -4381,7 +4401,7 @@ def get_optional_params(
|
|||
if frequency_penalty is not None:
|
||||
optional_params["repeat_penalty"] = frequency_penalty
|
||||
if stop is not None:
|
||||
optional_params["stop_sequences"] = stop
|
||||
optional_params["stop"] = stop
|
||||
elif custom_llm_provider == "nlp_cloud":
|
||||
supported_params = [
|
||||
"max_tokens",
|
||||
|
|
@ -8799,6 +8819,14 @@ def mock_completion_streaming_obj(model_response, mock_response, model):
|
|||
yield model_response
|
||||
|
||||
|
||||
async def async_mock_completion_streaming_obj(model_response, mock_response, model):
|
||||
for i in range(0, len(mock_response), 3):
|
||||
completion_obj = Delta(role="assistant", content=mock_response)
|
||||
model_response.choices[0].delta = completion_obj
|
||||
model_response.choices[0].finish_reason = "stop"
|
||||
yield model_response
|
||||
|
||||
|
||||
########## Reading Config File ############################
|
||||
def read_config_args(config_path) -> dict:
|
||||
try:
|
||||
|
|
@ -9231,3 +9259,21 @@ def get_logging_id(start_time, response_obj):
|
|||
return response_id
|
||||
except:
|
||||
return None
|
||||
|
||||
|
||||
def _get_base_model_from_metadata(model_call_details=None):
|
||||
if model_call_details is None:
|
||||
return None
|
||||
litellm_params = model_call_details.get("litellm_params", {})
|
||||
|
||||
if litellm_params is not None:
|
||||
metadata = litellm_params.get("metadata", {})
|
||||
|
||||
if metadata is not None:
|
||||
model_info = metadata.get("model_info", {})
|
||||
|
||||
if model_info is not None:
|
||||
base_model = model_info.get("base_model", None)
|
||||
if base_model is not None:
|
||||
return base_model
|
||||
return None
|
||||
|
|
|
|||
|
|
@ -8,6 +8,15 @@
|
|||
"litellm_provider": "openai",
|
||||
"mode": "chat"
|
||||
},
|
||||
"gpt-4-turbo-preview": {
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 8192,
|
||||
"max_output_tokens": 4096,
|
||||
"input_cost_per_token": 0.00001,
|
||||
"output_cost_per_token": 0.00003,
|
||||
"litellm_provider": "openai",
|
||||
"mode": "chat"
|
||||
},
|
||||
"gpt-4-0314": {
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 8192,
|
||||
|
|
@ -243,6 +252,15 @@
|
|||
"output_cost_per_pixel": 0.0,
|
||||
"litellm_provider": "openai"
|
||||
},
|
||||
"azure/gpt-4-0125-preview": {
|
||||
"max_tokens": 128000,
|
||||
"max_input_tokens": 128000,
|
||||
"max_output_tokens": 4096,
|
||||
"input_cost_per_token": 0.00001,
|
||||
"output_cost_per_token": 0.00003,
|
||||
"litellm_provider": "azure",
|
||||
"mode": "chat"
|
||||
},
|
||||
"azure/gpt-4-1106-preview": {
|
||||
"max_tokens": 128000,
|
||||
"max_input_tokens": 128000,
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "litellm"
|
||||
version = "1.23.0"
|
||||
version = "1.23.5"
|
||||
description = "Library to easily interface with LLM API providers"
|
||||
authors = ["BerriAI"]
|
||||
license = "MIT"
|
||||
|
|
@ -69,7 +69,7 @@ requires = ["poetry-core", "wheel"]
|
|||
build-backend = "poetry.core.masonry.api"
|
||||
|
||||
[tool.commitizen]
|
||||
version = "1.23.0"
|
||||
version = "1.23.5"
|
||||
version_files = [
|
||||
"pyproject.toml:^version"
|
||||
]
|
||||
|
|
|
|||
|
|
@ -1,6 +1,7 @@
|
|||
datasource client {
|
||||
provider = "postgresql"
|
||||
url = env("DATABASE_URL")
|
||||
directUrl = env("DIRECT_URL")
|
||||
}
|
||||
|
||||
generator client {
|
||||
|
|
|
|||
File diff suppressed because one or more lines are too long
|
|
@ -0,0 +1 @@
|
|||
self.__BUILD_MANIFEST={__rewrites:{afterFiles:[],beforeFiles:[],fallback:[]},"/_error":["static/chunks/pages/_error-d6107f1aac0c574c.js"],sortedPages:["/_app","/_error"]},self.__BUILD_MANIFEST_CB&&self.__BUILD_MANIFEST_CB();
|
||||
|
|
@ -0,0 +1 @@
|
|||
self.__SSG_MANIFEST=new Set([]);self.__SSG_MANIFEST_CB&&self.__SSG_MANIFEST_CB()
|
||||
|
|
@ -0,0 +1 @@
|
|||
(self.webpackChunk_N_E=self.webpackChunk_N_E||[]).push([[185],{87421:function(n,e,t){Promise.resolve().then(t.t.bind(t,99646,23)),Promise.resolve().then(t.t.bind(t,63385,23))},63385:function(){},99646:function(n){n.exports={style:{fontFamily:"'__Inter_c23dc8', '__Inter_Fallback_c23dc8'",fontStyle:"normal"},className:"__className_c23dc8"}}},function(n){n.O(0,[971,69,744],function(){return n(n.s=87421)}),_N_E=n.O()}]);
|
||||
File diff suppressed because one or more lines are too long
|
|
@ -0,0 +1 @@
|
|||
(self.webpackChunk_N_E=self.webpackChunk_N_E||[]).push([[744],{32028:function(e,n,t){Promise.resolve().then(t.t.bind(t,47690,23)),Promise.resolve().then(t.t.bind(t,48955,23)),Promise.resolve().then(t.t.bind(t,5613,23)),Promise.resolve().then(t.t.bind(t,11902,23)),Promise.resolve().then(t.t.bind(t,31778,23)),Promise.resolve().then(t.t.bind(t,77831,23))}},function(e){var n=function(n){return e(e.s=n)};e.O(0,[971,69],function(){return n(35317),n(32028)}),_N_E=e.O()}]);
|
||||
|
|
@ -1 +1 @@
|
|||
!function(){"use strict";var e,t,n,r,o,u,i,c,f,a={},l={};function d(e){var t=l[e];if(void 0!==t)return t.exports;var n=l[e]={id:e,loaded:!1,exports:{}},r=!0;try{a[e](n,n.exports,d),r=!1}finally{r&&delete l[e]}return n.loaded=!0,n.exports}d.m=a,e=[],d.O=function(t,n,r,o){if(n){o=o||0;for(var u=e.length;u>0&&e[u-1][2]>o;u--)e[u]=e[u-1];e[u]=[n,r,o];return}for(var i=1/0,u=0;u<e.length;u++){for(var n=e[u][0],r=e[u][1],o=e[u][2],c=!0,f=0;f<n.length;f++)i>=o&&Object.keys(d.O).every(function(e){return d.O[e](n[f])})?n.splice(f--,1):(c=!1,o<i&&(i=o));if(c){e.splice(u--,1);var a=r();void 0!==a&&(t=a)}}return t},d.n=function(e){var t=e&&e.__esModule?function(){return e.default}:function(){return e};return d.d(t,{a:t}),t},n=Object.getPrototypeOf?function(e){return Object.getPrototypeOf(e)}:function(e){return e.__proto__},d.t=function(e,r){if(1&r&&(e=this(e)),8&r||"object"==typeof e&&e&&(4&r&&e.__esModule||16&r&&"function"==typeof e.then))return e;var o=Object.create(null);d.r(o);var u={};t=t||[null,n({}),n([]),n(n)];for(var i=2&r&&e;"object"==typeof i&&!~t.indexOf(i);i=n(i))Object.getOwnPropertyNames(i).forEach(function(t){u[t]=function(){return e[t]}});return u.default=function(){return e},d.d(o,u),o},d.d=function(e,t){for(var n in t)d.o(t,n)&&!d.o(e,n)&&Object.defineProperty(e,n,{enumerable:!0,get:t[n]})},d.f={},d.e=function(e){return Promise.all(Object.keys(d.f).reduce(function(t,n){return d.f[n](e,t),t},[]))},d.u=function(e){},d.miniCssF=function(e){return"static/css/a6a9860a7fe022a9.css"},d.g=function(){if("object"==typeof globalThis)return globalThis;try{return this||Function("return this")()}catch(e){if("object"==typeof window)return window}}(),d.o=function(e,t){return Object.prototype.hasOwnProperty.call(e,t)},r={},o="_N_E:",d.l=function(e,t,n,u){if(r[e]){r[e].push(t);return}if(void 0!==n)for(var i,c,f=document.getElementsByTagName("script"),a=0;a<f.length;a++){var l=f[a];if(l.getAttribute("src")==e||l.getAttribute("data-webpack")==o+n){i=l;break}}i||(c=!0,(i=document.createElement("script")).charset="utf-8",i.timeout=120,d.nc&&i.setAttribute("nonce",d.nc),i.setAttribute("data-webpack",o+n),i.src=d.tu(e)),r[e]=[t];var s=function(t,n){i.onerror=i.onload=null,clearTimeout(p);var o=r[e];if(delete r[e],i.parentNode&&i.parentNode.removeChild(i),o&&o.forEach(function(e){return e(n)}),t)return t(n)},p=setTimeout(s.bind(null,void 0,{type:"timeout",target:i}),12e4);i.onerror=s.bind(null,i.onerror),i.onload=s.bind(null,i.onload),c&&document.head.appendChild(i)},d.r=function(e){"undefined"!=typeof Symbol&&Symbol.toStringTag&&Object.defineProperty(e,Symbol.toStringTag,{value:"Module"}),Object.defineProperty(e,"__esModule",{value:!0})},d.nmd=function(e){return e.paths=[],e.children||(e.children=[]),e},d.tt=function(){return void 0===u&&(u={createScriptURL:function(e){return e}},"undefined"!=typeof trustedTypes&&trustedTypes.createPolicy&&(u=trustedTypes.createPolicy("nextjs#bundler",u))),u},d.tu=function(e){return d.tt().createScriptURL(e)},d.p="/ui/_next/",i={272:0},d.f.j=function(e,t){var n=d.o(i,e)?i[e]:void 0;if(0!==n){if(n)t.push(n[2]);else if(272!=e){var r=new Promise(function(t,r){n=i[e]=[t,r]});t.push(n[2]=r);var o=d.p+d.u(e),u=Error();d.l(o,function(t){if(d.o(i,e)&&(0!==(n=i[e])&&(i[e]=void 0),n)){var r=t&&("load"===t.type?"missing":t.type),o=t&&t.target&&t.target.src;u.message="Loading chunk "+e+" failed.\n("+r+": "+o+")",u.name="ChunkLoadError",u.type=r,u.request=o,n[1](u)}},"chunk-"+e,e)}else i[e]=0}},d.O.j=function(e){return 0===i[e]},c=function(e,t){var n,r,o=t[0],u=t[1],c=t[2],f=0;if(o.some(function(e){return 0!==i[e]})){for(n in u)d.o(u,n)&&(d.m[n]=u[n]);if(c)var a=c(d)}for(e&&e(t);f<o.length;f++)r=o[f],d.o(i,r)&&i[r]&&i[r][0](),i[r]=0;return d.O(a)},(f=self.webpackChunk_N_E=self.webpackChunk_N_E||[]).forEach(c.bind(null,0)),f.push=c.bind(null,f.push.bind(f))}();
|
||||
!function(){"use strict";var e,t,n,r,o,u,i,c,f,a={},l={};function d(e){var t=l[e];if(void 0!==t)return t.exports;var n=l[e]={id:e,loaded:!1,exports:{}},r=!0;try{a[e](n,n.exports,d),r=!1}finally{r&&delete l[e]}return n.loaded=!0,n.exports}d.m=a,e=[],d.O=function(t,n,r,o){if(n){o=o||0;for(var u=e.length;u>0&&e[u-1][2]>o;u--)e[u]=e[u-1];e[u]=[n,r,o];return}for(var i=1/0,u=0;u<e.length;u++){for(var n=e[u][0],r=e[u][1],o=e[u][2],c=!0,f=0;f<n.length;f++)i>=o&&Object.keys(d.O).every(function(e){return d.O[e](n[f])})?n.splice(f--,1):(c=!1,o<i&&(i=o));if(c){e.splice(u--,1);var a=r();void 0!==a&&(t=a)}}return t},d.n=function(e){var t=e&&e.__esModule?function(){return e.default}:function(){return e};return d.d(t,{a:t}),t},n=Object.getPrototypeOf?function(e){return Object.getPrototypeOf(e)}:function(e){return e.__proto__},d.t=function(e,r){if(1&r&&(e=this(e)),8&r||"object"==typeof e&&e&&(4&r&&e.__esModule||16&r&&"function"==typeof e.then))return e;var o=Object.create(null);d.r(o);var u={};t=t||[null,n({}),n([]),n(n)];for(var i=2&r&&e;"object"==typeof i&&!~t.indexOf(i);i=n(i))Object.getOwnPropertyNames(i).forEach(function(t){u[t]=function(){return e[t]}});return u.default=function(){return e},d.d(o,u),o},d.d=function(e,t){for(var n in t)d.o(t,n)&&!d.o(e,n)&&Object.defineProperty(e,n,{enumerable:!0,get:t[n]})},d.f={},d.e=function(e){return Promise.all(Object.keys(d.f).reduce(function(t,n){return d.f[n](e,t),t},[]))},d.u=function(e){},d.miniCssF=function(e){return"static/css/173c5a76ba57a3b8.css"},d.g=function(){if("object"==typeof globalThis)return globalThis;try{return this||Function("return this")()}catch(e){if("object"==typeof window)return window}}(),d.o=function(e,t){return Object.prototype.hasOwnProperty.call(e,t)},r={},o="_N_E:",d.l=function(e,t,n,u){if(r[e]){r[e].push(t);return}if(void 0!==n)for(var i,c,f=document.getElementsByTagName("script"),a=0;a<f.length;a++){var l=f[a];if(l.getAttribute("src")==e||l.getAttribute("data-webpack")==o+n){i=l;break}}i||(c=!0,(i=document.createElement("script")).charset="utf-8",i.timeout=120,d.nc&&i.setAttribute("nonce",d.nc),i.setAttribute("data-webpack",o+n),i.src=d.tu(e)),r[e]=[t];var s=function(t,n){i.onerror=i.onload=null,clearTimeout(p);var o=r[e];if(delete r[e],i.parentNode&&i.parentNode.removeChild(i),o&&o.forEach(function(e){return e(n)}),t)return t(n)},p=setTimeout(s.bind(null,void 0,{type:"timeout",target:i}),12e4);i.onerror=s.bind(null,i.onerror),i.onload=s.bind(null,i.onload),c&&document.head.appendChild(i)},d.r=function(e){"undefined"!=typeof Symbol&&Symbol.toStringTag&&Object.defineProperty(e,Symbol.toStringTag,{value:"Module"}),Object.defineProperty(e,"__esModule",{value:!0})},d.nmd=function(e){return e.paths=[],e.children||(e.children=[]),e},d.tt=function(){return void 0===u&&(u={createScriptURL:function(e){return e}},"undefined"!=typeof trustedTypes&&trustedTypes.createPolicy&&(u=trustedTypes.createPolicy("nextjs#bundler",u))),u},d.tu=function(e){return d.tt().createScriptURL(e)},d.p="/ui/_next/",i={272:0},d.f.j=function(e,t){var n=d.o(i,e)?i[e]:void 0;if(0!==n){if(n)t.push(n[2]);else if(272!=e){var r=new Promise(function(t,r){n=i[e]=[t,r]});t.push(n[2]=r);var o=d.p+d.u(e),u=Error();d.l(o,function(t){if(d.o(i,e)&&(0!==(n=i[e])&&(i[e]=void 0),n)){var r=t&&("load"===t.type?"missing":t.type),o=t&&t.target&&t.target.src;u.message="Loading chunk "+e+" failed.\n("+r+": "+o+")",u.name="ChunkLoadError",u.type=r,u.request=o,n[1](u)}},"chunk-"+e,e)}else i[e]=0}},d.O.j=function(e){return 0===i[e]},c=function(e,t){var n,r,o=t[0],u=t[1],c=t[2],f=0;if(o.some(function(e){return 0!==i[e]})){for(n in u)d.o(u,n)&&(d.m[n]=u[n]);if(c)var a=c(d)}for(e&&e(t);f<o.length;f++)r=o[f],d.o(i,r)&&i[r]&&i[r][0](),i[r]=0;return d.O(a)},(f=self.webpackChunk_N_E=self.webpackChunk_N_E||[]).forEach(c.bind(null,0)),f.push=c.bind(null,f.push.bind(f))}();
|
||||
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
|
|
@ -1,7 +1,7 @@
|
|||
2:"$Sreact.suspense"
|
||||
3:I[27680,["787","static/chunks/787-5bb33960644f5c7c.js","931","static/chunks/app/page-7f03ccc8529ada97.js"],""]
|
||||
3:I[42989,["787","static/chunks/787-5bb33960644f5c7c.js","931","static/chunks/app/page-b1e8aae39e9306e9.js"],""]
|
||||
4:I[5613,[],""]
|
||||
5:I[31778,[],""]
|
||||
0:["p5gDwQBbgW8D3Uz3lgoZg",[[["",{"children":["__PAGE__",{}]},"$undefined","$undefined",true],["",{"children":["__PAGE__",{},["$L1",["$","$2",null,{"fallback":["$","div",null,{"children":"Loading..."}],"children":["$","div",null,{"className":"flex min-h-screen flex-col ","children":["$","$L3",null,{}]}]}],null]]},[null,["$","html",null,{"lang":"en","children":["$","body",null,{"className":"__className_c23dc8","children":["$","$L4",null,{"parallelRouterKey":"children","segmentPath":["children"],"loading":"$undefined","loadingStyles":"$undefined","loadingScripts":"$undefined","hasLoading":false,"error":"$undefined","errorStyles":"$undefined","errorScripts":"$undefined","template":["$","$L5",null,{}],"templateStyles":"$undefined","templateScripts":"$undefined","notFound":[["$","title",null,{"children":"404: This page could not be found."}],["$","div",null,{"style":{"fontFamily":"system-ui,\"Segoe UI\",Roboto,Helvetica,Arial,sans-serif,\"Apple Color Emoji\",\"Segoe UI Emoji\"","height":"100vh","textAlign":"center","display":"flex","flexDirection":"column","alignItems":"center","justifyContent":"center"},"children":["$","div",null,{"children":[["$","style",null,{"dangerouslySetInnerHTML":{"__html":"body{color:#000;background:#fff;margin:0}.next-error-h1{border-right:1px solid rgba(0,0,0,.3)}@media (prefers-color-scheme:dark){body{color:#fff;background:#000}.next-error-h1{border-right:1px solid rgba(255,255,255,.3)}}"}}],["$","h1",null,{"className":"next-error-h1","style":{"display":"inline-block","margin":"0 20px 0 0","padding":"0 23px 0 0","fontSize":24,"fontWeight":500,"verticalAlign":"top","lineHeight":"49px"},"children":"404"}],["$","div",null,{"style":{"display":"inline-block"},"children":["$","h2",null,{"style":{"fontSize":14,"fontWeight":400,"lineHeight":"49px","margin":0},"children":"This page could not be found."}]}]]}]}]],"notFoundStyles":[],"styles":null}]}]}],null]],[[["$","link","0",{"rel":"stylesheet","href":"/ui/_next/static/css/a6a9860a7fe022a9.css","precedence":"next","crossOrigin":""}]],"$L6"]]]]
|
||||
0:["Ul7bzKEbTPs-NwnRJpbmM",[[["",{"children":["__PAGE__",{}]},"$undefined","$undefined",true],["",{"children":["__PAGE__",{},["$L1",["$","$2",null,{"fallback":["$","div",null,{"children":"Loading..."}],"children":["$","div",null,{"className":"flex min-h-screen flex-col ","children":["$","$L3",null,{}]}]}],null]]},[null,["$","html",null,{"lang":"en","children":["$","body",null,{"className":"__className_c23dc8","children":["$","$L4",null,{"parallelRouterKey":"children","segmentPath":["children"],"loading":"$undefined","loadingStyles":"$undefined","loadingScripts":"$undefined","hasLoading":false,"error":"$undefined","errorStyles":"$undefined","errorScripts":"$undefined","template":["$","$L5",null,{}],"templateStyles":"$undefined","templateScripts":"$undefined","notFound":[["$","title",null,{"children":"404: This page could not be found."}],["$","div",null,{"style":{"fontFamily":"system-ui,\"Segoe UI\",Roboto,Helvetica,Arial,sans-serif,\"Apple Color Emoji\",\"Segoe UI Emoji\"","height":"100vh","textAlign":"center","display":"flex","flexDirection":"column","alignItems":"center","justifyContent":"center"},"children":["$","div",null,{"children":[["$","style",null,{"dangerouslySetInnerHTML":{"__html":"body{color:#000;background:#fff;margin:0}.next-error-h1{border-right:1px solid rgba(0,0,0,.3)}@media (prefers-color-scheme:dark){body{color:#fff;background:#000}.next-error-h1{border-right:1px solid rgba(255,255,255,.3)}}"}}],["$","h1",null,{"className":"next-error-h1","style":{"display":"inline-block","margin":"0 20px 0 0","padding":"0 23px 0 0","fontSize":24,"fontWeight":500,"verticalAlign":"top","lineHeight":"49px"},"children":"404"}],["$","div",null,{"style":{"display":"inline-block"},"children":["$","h2",null,{"style":{"fontSize":14,"fontWeight":400,"lineHeight":"49px","margin":0},"children":"This page could not be found."}]}]]}]}]],"notFoundStyles":[],"styles":null}]}]}],null]],[[["$","link","0",{"rel":"stylesheet","href":"/ui/_next/static/css/173c5a76ba57a3b8.css","precedence":"next","crossOrigin":""}]],"$L6"]]]]
|
||||
6:[["$","meta","0",{"name":"viewport","content":"width=device-width, initial-scale=1"}],["$","meta","1",{"charSet":"utf-8"}],["$","title","2",{"children":"🚅 LiteLLM"}],["$","meta","3",{"name":"description","content":"LiteLLM Proxy Admin UI"}],["$","link","4",{"rel":"icon","href":"/ui/favicon.ico","type":"image/x-icon","sizes":"16x16"}],["$","meta","5",{"name":"next-size-adjust"}]]
|
||||
1:null
|
||||
|
|
|
|||
|
|
@ -162,3 +162,32 @@ export const keySpendLogsCall = async (accessToken: String, token: String) => {
|
|||
throw error;
|
||||
}
|
||||
};
|
||||
|
||||
|
||||
|
||||
export const spendUsersCall = async (accessToken: String, userID: String) => {
|
||||
try {
|
||||
const url = proxyBaseUrl ? `${proxyBaseUrl}/spend/users` : `/spend/users`;
|
||||
console.log("in spendUsersCall:", url);
|
||||
const response = await fetch(`${url}/?user_id=${userID}`, {
|
||||
method: "GET",
|
||||
headers: {
|
||||
Authorization: `Bearer ${accessToken}`,
|
||||
"Content-Type": "application/json",
|
||||
},
|
||||
});
|
||||
if (!response.ok) {
|
||||
const errorData = await response.text();
|
||||
message.error(errorData);
|
||||
throw new Error("Network response was not ok");
|
||||
}
|
||||
|
||||
const data = await response.json();
|
||||
console.log(data);
|
||||
return data;
|
||||
} catch (error) {
|
||||
console.error("Failed to get spend for user", error);
|
||||
throw error;
|
||||
}
|
||||
};
|
||||
|
||||
|
|
|
|||
|
|
@ -120,7 +120,7 @@ const UserDashboard = () => {
|
|||
<Navbar userID={userID} userRole={userRole} userEmail={userEmail} />
|
||||
<Grid numItems={1} className="gap-0 p-10 h-[75vh] w-full">
|
||||
<Col numColSpan={1}>
|
||||
<ViewUserSpend userID={userID} userSpendData={userSpendData} />
|
||||
<ViewUserSpend userID={userID} userSpendData={userSpendData} userRole={userRole} accessToken={accessToken}/>
|
||||
<ViewKeyTable
|
||||
userID={userID}
|
||||
accessToken={accessToken}
|
||||
|
|
|
|||
|
|
@ -33,22 +33,60 @@ const ViewKeyTable: React.FC<ViewKeyTableProps> = ({
|
|||
setData,
|
||||
}) => {
|
||||
const [isButtonClicked, setIsButtonClicked] = useState(false);
|
||||
const [isDeleteModalOpen, setIsDeleteModalOpen] = useState(false);
|
||||
const [keyToDelete, setKeyToDelete] = useState<string | null>(null);
|
||||
|
||||
const handleDelete = async (token: String) => {
|
||||
const handleDelete = async (token: string) => {
|
||||
if (data == null) {
|
||||
return;
|
||||
}
|
||||
|
||||
// Set the key to delete and open the confirmation modal
|
||||
setKeyToDelete(token);
|
||||
setIsDeleteModalOpen(true);
|
||||
};
|
||||
|
||||
const confirmDelete = async () => {
|
||||
if (keyToDelete == null || data == null) {
|
||||
return;
|
||||
}
|
||||
|
||||
try {
|
||||
await keyDeleteCall(accessToken, token);
|
||||
await keyDeleteCall(accessToken, keyToDelete);
|
||||
// Successfully completed the deletion. Update the state to trigger a rerender.
|
||||
const filteredData = data.filter((item) => item.token !== token);
|
||||
const filteredData = data.filter((item) => item.token !== keyToDelete);
|
||||
setData(filteredData);
|
||||
} catch (error) {
|
||||
console.error("Error deleting the key:", error);
|
||||
// Handle any error situations, such as displaying an error message to the user.
|
||||
}
|
||||
|
||||
// Close the confirmation modal and reset the keyToDelete
|
||||
setIsDeleteModalOpen(false);
|
||||
setKeyToDelete(null);
|
||||
};
|
||||
|
||||
const cancelDelete = () => {
|
||||
// Close the confirmation modal and reset the keyToDelete
|
||||
setIsDeleteModalOpen(false);
|
||||
setKeyToDelete(null);
|
||||
};
|
||||
|
||||
// const handleDelete = async (token: String) => {
|
||||
// if (data == null) {
|
||||
// return;
|
||||
// }
|
||||
// try {
|
||||
// await keyDeleteCall(accessToken, token);
|
||||
// // Successfully completed the deletion. Update the state to trigger a rerender.
|
||||
// const filteredData = data.filter((item) => item.token !== token);
|
||||
// setData(filteredData);
|
||||
// } catch (error) {
|
||||
// console.error("Error deleting the key:", error);
|
||||
// // Handle any error situations, such as displaying an error message to the user.
|
||||
// }
|
||||
// };
|
||||
|
||||
if (data == null) {
|
||||
return;
|
||||
}
|
||||
|
|
@ -65,6 +103,8 @@ const ViewKeyTable: React.FC<ViewKeyTableProps> = ({
|
|||
<TableHeaderCell>Key Budget (USD)</TableHeaderCell>
|
||||
<TableHeaderCell>Team ID</TableHeaderCell>
|
||||
<TableHeaderCell>Metadata</TableHeaderCell>
|
||||
<TableHeaderCell>Models</TableHeaderCell>
|
||||
<TableHeaderCell>TPM / RPM Limits</TableHeaderCell>
|
||||
<TableHeaderCell>Expires</TableHeaderCell>
|
||||
</TableRow>
|
||||
</TableHead>
|
||||
|
|
@ -103,6 +143,12 @@ const ViewKeyTable: React.FC<ViewKeyTableProps> = ({
|
|||
<TableCell>
|
||||
<Text>{JSON.stringify(item.metadata)}</Text>
|
||||
</TableCell>
|
||||
<TableCell>
|
||||
<Text>{JSON.stringify(item.models)}</Text>
|
||||
</TableCell>
|
||||
<TableCell>
|
||||
<Text>TPM Limit: {item.tpm_limit? item.tpm_limit : "Unlimited"} <br></br> RPM Limit: {item.rpm_limit? item.rpm_limit : "Unlimited"}</Text>
|
||||
</TableCell>
|
||||
<TableCell>
|
||||
{item.expires != null ? (
|
||||
<Text>{item.expires}</Text>
|
||||
|
|
@ -131,6 +177,40 @@ const ViewKeyTable: React.FC<ViewKeyTableProps> = ({
|
|||
})}
|
||||
</TableBody>
|
||||
</Table>
|
||||
{isDeleteModalOpen && (
|
||||
<div className="fixed z-10 inset-0 overflow-y-auto">
|
||||
<div className="flex items-end justify-center min-h-screen pt-4 px-4 pb-20 text-center sm:block sm:p-0">
|
||||
<div className="fixed inset-0 transition-opacity" aria-hidden="true">
|
||||
<div className="absolute inset-0 bg-gray-500 opacity-75"></div>
|
||||
</div>
|
||||
|
||||
{/* Modal Panel */}
|
||||
<span className="hidden sm:inline-block sm:align-middle sm:h-screen" aria-hidden="true">
|
||||
​
|
||||
</span>
|
||||
|
||||
{/* Confirmation Modal Content */}
|
||||
<div className="inline-block align-bottom bg-white rounded-lg text-left overflow-hidden shadow-xl transform transition-all sm:my-8 sm:align-middle sm:max-w-lg sm:w-full">
|
||||
<div className="bg-white px-4 pt-5 pb-4 sm:p-6 sm:pb-4">
|
||||
<div className="sm:flex sm:items-start">
|
||||
<div className="mt-3 text-center sm:mt-0 sm:ml-4 sm:text-left">
|
||||
<h3 className="text-lg leading-6 font-medium text-gray-900">Delete Key</h3>
|
||||
<div className="mt-2">
|
||||
<p className="text-sm text-gray-500">Are you sure you want to delete this key ?</p>
|
||||
</div>
|
||||
</div>
|
||||
</div>
|
||||
</div>
|
||||
<div className="bg-gray-50 px-4 py-3 sm:px-6 sm:flex sm:flex-row-reverse">
|
||||
<Button onClick={confirmDelete} color="red" className="ml-2">
|
||||
Delete
|
||||
</Button>
|
||||
<Button onClick={cancelDelete}>Cancel</Button>
|
||||
</div>
|
||||
</div>
|
||||
</div>
|
||||
</div>
|
||||
)}
|
||||
</Card>
|
||||
);
|
||||
};
|
||||
|
|
|
|||
|
|
@ -1,5 +1,5 @@
|
|||
"use client";
|
||||
import React, { useEffect } from "react";
|
||||
import React, { useEffect, useState } from "react";
|
||||
import { keyDeleteCall } from "./networking";
|
||||
import { StatusOnlineIcon, TrashIcon } from "@heroicons/react/outline";
|
||||
import { DonutChart } from "@tremor/react";
|
||||
|
|
@ -17,6 +17,7 @@ import {
|
|||
Title,
|
||||
Icon,
|
||||
} from "@tremor/react";
|
||||
import { spendUsersCall } from "./networking";
|
||||
|
||||
|
||||
// Define the props type
|
||||
|
|
@ -28,13 +29,33 @@ interface UserSpendData {
|
|||
interface ViewUserSpendProps {
|
||||
userID: string | null;
|
||||
userSpendData: UserSpendData | null; // Use the UserSpendData interface here
|
||||
userRole: string | null;
|
||||
accessToken: string;
|
||||
}
|
||||
const ViewUserSpend: React.FC<ViewUserSpendProps> = ({ userID, userSpendData }) => {
|
||||
const ViewUserSpend: React.FC<ViewUserSpendProps> = ({ userID, userSpendData, userRole, accessToken }) => {
|
||||
console.log("User SpendData:", userSpendData);
|
||||
const spend = userSpendData?.spend;
|
||||
const maxBudget = userSpendData?.max_budget || null;
|
||||
const [spend, setSpend] = useState(userSpendData?.spend);
|
||||
const [maxBudget, setMaxBudget] = useState(userSpendData?.max_budget || null);
|
||||
|
||||
useEffect(() => {
|
||||
const fetchData = async () => {
|
||||
if (userRole === "Admin") {
|
||||
try {
|
||||
const data = await spendUsersCall(accessToken, "litellm-proxy-budget");
|
||||
console.log("Result from callSpendUsers:", data);
|
||||
const total_budget = data[0]
|
||||
setSpend(total_budget?.spend);
|
||||
setMaxBudget(total_budget?.max_budget || null);
|
||||
} catch (error) {
|
||||
console.error("Failed to get spend for user", error);
|
||||
}
|
||||
}
|
||||
};
|
||||
|
||||
fetchData();
|
||||
}, [userRole, accessToken, userID]);
|
||||
|
||||
const displayMaxBudget = maxBudget !== null ? `$${maxBudget} limit` : "No limit";
|
||||
const displayText = `$${spend} / ${displayMaxBudget}`;
|
||||
|
||||
return (
|
||||
<>
|
||||
|
|
|
|||
Loading…
Add table
Reference in a new issue