mirror of
https://github.com/BerriAI/litellm.git
synced 2026-09-14 23:21:35 +00:00
Merge remote-tracking branch 'origin/litellm_internal_staging' into litellm_fix-vertex-embed-content-logging
This commit is contained in:
 Ishaan Jaffer
commit
aa7ced3646
2248 changed files with 92444 additions and 46320 deletions
1844
.circleci/config.yml
1844
.circleci/config.yml
File diff suppressed because it is too large
Load diff
BIN
.github/screenshots/after_org_assigned.png
vendored
Normal file
BIN
.github/screenshots/after_org_assigned.png
vendored
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 96 KiB |
BIN
.github/screenshots/after_org_detail.png
vendored
Normal file
BIN
.github/screenshots/after_org_detail.png
vendored
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 103 KiB |
BIN
.github/screenshots/before_403_error.png
vendored
Normal file
BIN
.github/screenshots/before_403_error.png
vendored
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 123 KiB |
BIN
.github/screenshots/before_no_org.png
vendored
Normal file
BIN
.github/screenshots/before_no_org.png
vendored
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 95 KiB |
40
.github/scripts/close_duplicate_issues.py
vendored
40
.github/scripts/close_duplicate_issues.py
vendored
|
|
@ -42,7 +42,9 @@ def gh(*args: str) -> str:
|
|||
def fetch_open_issues(repo: str | None) -> list[dict]:
|
||||
"""Fetch all open issues (excluding PRs) via gh api --paginate."""
|
||||
if repo:
|
||||
endpoint = f"repos/{repo}/issues?state=open&per_page=100&sort=created&direction=asc"
|
||||
endpoint = (
|
||||
f"repos/{repo}/issues?state=open&per_page=100&sort=created&direction=asc"
|
||||
)
|
||||
else:
|
||||
endpoint = "repos/{owner}/{repo}/issues?state=open&per_page=100&sort=created&direction=asc"
|
||||
cmd = ["api", "--paginate", endpoint]
|
||||
|
|
@ -71,7 +73,9 @@ def close_as_duplicate(
|
|||
repo_args = ["--repo", repo] if repo else []
|
||||
|
||||
if dry_run:
|
||||
print(f" [DRY RUN] Would close #{issue_number} as duplicate of #{duplicate_of}")
|
||||
print(
|
||||
f" [DRY RUN] Would close #{issue_number} as duplicate of #{duplicate_of}"
|
||||
)
|
||||
return
|
||||
|
||||
# Add comment
|
||||
|
|
@ -115,7 +119,9 @@ def find_duplicate(
|
|||
return None
|
||||
|
||||
|
||||
def scan_all(issues: list[dict], threshold: float, repo: str | None, dry_run: bool) -> int:
|
||||
def scan_all(
|
||||
issues: list[dict], threshold: float, repo: str | None, dry_run: bool
|
||||
) -> int:
|
||||
"""Compare every issue against all older issues. Returns count of duplicates found."""
|
||||
# Sort oldest first
|
||||
issues.sort(key=lambda i: i["number"])
|
||||
|
|
@ -144,7 +150,11 @@ def scan_all(issues: list[dict], threshold: float, repo: str | None, dry_run: bo
|
|||
|
||||
|
||||
def check_single(
|
||||
issue_number: int, issues: list[dict], threshold: float, repo: str | None, dry_run: bool
|
||||
issue_number: int,
|
||||
issues: list[dict],
|
||||
threshold: float,
|
||||
repo: str | None,
|
||||
dry_run: bool,
|
||||
) -> bool:
|
||||
"""Check a single issue against all older open issues. Returns True if duplicate found."""
|
||||
target = None
|
||||
|
|
@ -178,13 +188,23 @@ def check_single(
|
|||
|
||||
|
||||
def main() -> None:
|
||||
parser = argparse.ArgumentParser(description="Detect and close duplicate GitHub issues")
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Detect and close duplicate GitHub issues"
|
||||
)
|
||||
mode = parser.add_mutually_exclusive_group(required=True)
|
||||
mode.add_argument("--scan", action="store_true", help="Scan all open issues")
|
||||
mode.add_argument("--issue-number", type=int, help="Check a single issue number")
|
||||
parser.add_argument("--threshold", type=float, default=0.85, help="Similarity threshold (0-1)")
|
||||
parser.add_argument("--close", action="store_true", help="Actually close duplicates (default is dry-run)")
|
||||
parser.add_argument("--repo", type=str, help="Repository (owner/repo). Auto-detected if omitted.")
|
||||
parser.add_argument(
|
||||
"--threshold", type=float, default=0.85, help="Similarity threshold (0-1)"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--close",
|
||||
action="store_true",
|
||||
help="Actually close duplicates (default is dry-run)",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--repo", type=str, help="Repository (owner/repo). Auto-detected if omitted."
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
dry_run = not args.close
|
||||
|
|
@ -200,7 +220,9 @@ def main() -> None:
|
|||
count = scan_all(issues, args.threshold, args.repo, dry_run)
|
||||
print(f"\nTotal duplicates {'found' if dry_run else 'closed'}: {count}")
|
||||
else:
|
||||
found = check_single(args.issue_number, issues, args.threshold, args.repo, dry_run)
|
||||
found = check_single(
|
||||
args.issue_number, issues, args.threshold, args.repo, dry_run
|
||||
)
|
||||
sys.exit(0 if found else 0) # Always exit 0; finding no dup is not an error
|
||||
|
||||
|
||||
|
|
|
|||
20
.github/scripts/scan_keywords.py
vendored
20
.github/scripts/scan_keywords.py
vendored
|
|
@ -67,14 +67,13 @@ def send_webhook(webhook_url: str, payload: dict) -> None:
|
|||
def _excerpt(text: str, max_len: int = 400) -> str:
|
||||
if not text:
|
||||
return ""
|
||||
|
||||
|
||||
# Keep original formatting
|
||||
if len(text) <= max_len:
|
||||
return text
|
||||
return text[: max_len - 1] + "…"
|
||||
|
||||
|
||||
|
||||
def main() -> int:
|
||||
event = read_event_payload()
|
||||
if not event:
|
||||
|
|
@ -87,8 +86,19 @@ def main() -> int:
|
|||
|
||||
# Keywords from env or defaults
|
||||
keywords_env = os.environ.get("KEYWORDS", "")
|
||||
default_keywords = ["azure", "openai", "bedrock", "vertexai", "vertex ai", "anthropic"]
|
||||
keywords = [k.strip() for k in keywords_env.split(",")] if keywords_env else default_keywords
|
||||
default_keywords = [
|
||||
"azure",
|
||||
"openai",
|
||||
"bedrock",
|
||||
"vertexai",
|
||||
"vertex ai",
|
||||
"anthropic",
|
||||
]
|
||||
keywords = (
|
||||
[k.strip() for k in keywords_env.split(",")]
|
||||
if keywords_env
|
||||
else default_keywords
|
||||
)
|
||||
|
||||
matches = detect_keywords(combined_text, keywords)
|
||||
found = bool(matches)
|
||||
|
|
@ -129,5 +139,3 @@ def main() -> int:
|
|||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
|
||||
|
||||
|
|
|
|||
37
.github/workflows/_test-unit-services-base.yml
vendored
37
.github/workflows/_test-unit-services-base.yml
vendored
|
|
@ -32,41 +32,39 @@ on:
|
|||
required: false
|
||||
type: boolean
|
||||
default: false
|
||||
dist:
|
||||
description: "pytest-xdist distribution mode (loadscope|load|worksteal|loadfile|no)"
|
||||
required: false
|
||||
type: string
|
||||
default: "loadscope"
|
||||
artifact-name:
|
||||
description: "Unique name for the coverage artifact (must be unique per run)"
|
||||
required: false
|
||||
type: string
|
||||
default: "run"
|
||||
secrets:
|
||||
DATABASE_URL:
|
||||
required: false
|
||||
POSTGRES_USER:
|
||||
required: false
|
||||
POSTGRES_PASSWORD:
|
||||
required: false
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
# The postgres service container below is spawned per-job on localhost and
|
||||
# destroyed with the job. Nothing outside the runner can reach it. The
|
||||
# user/password/database here are not secrets — they're bootstrap values
|
||||
# for a throwaway container — so we hardcode them instead of attaching
|
||||
# every matrix shard to a GHA environment just to read three "secrets"
|
||||
# (which also produces a "temporarily deployed to …" notification on the
|
||||
# PR timeline per shard per push).
|
||||
jobs:
|
||||
run:
|
||||
name: Run tests
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: ${{ inputs.timeout-minutes }}
|
||||
# Environment is derived from the enable-* flags, not caller-controllable.
|
||||
# This prevents callers from passing arbitrary environment names to bypass secret scoping.
|
||||
environment: >-
|
||||
${{
|
||||
inputs.enable-postgres && 'integration-postgres' ||
|
||||
''
|
||||
}}
|
||||
|
||||
services:
|
||||
postgres:
|
||||
image: postgres@sha256:705a5d5b5836f3fcba0d02c4d281e6a7dd9ed2dd4078640f08a1e1e9896e097d # postgres:14
|
||||
env:
|
||||
POSTGRES_USER: ${{ secrets.POSTGRES_USER }}
|
||||
POSTGRES_PASSWORD: ${{ secrets.POSTGRES_PASSWORD }}
|
||||
POSTGRES_USER: litellm
|
||||
POSTGRES_PASSWORD: litellm
|
||||
POSTGRES_DB: litellm_test
|
||||
ports:
|
||||
- 5432:5432
|
||||
|
|
@ -114,7 +112,7 @@ jobs:
|
|||
- name: Run Prisma migrations
|
||||
if: ${{ inputs.enable-postgres }}
|
||||
env:
|
||||
DATABASE_URL: ${{ secrets.DATABASE_URL }}
|
||||
DATABASE_URL: "postgresql://litellm:litellm@localhost:5432/litellm_test"
|
||||
run: |
|
||||
uv run --no-sync prisma db push --schema litellm/proxy/schema.prisma --accept-data-loss
|
||||
|
||||
|
|
@ -124,7 +122,8 @@ jobs:
|
|||
MAX_FAILURES: ${{ inputs.max-failures }}
|
||||
WORKERS: ${{ inputs.workers }}
|
||||
RERUNS: ${{ inputs.reruns }}
|
||||
DATABASE_URL: ${{ inputs.enable-postgres && secrets.DATABASE_URL || '' }}
|
||||
DIST: ${{ inputs.dist }}
|
||||
DATABASE_URL: ${{ inputs.enable-postgres && 'postgresql://litellm:litellm@localhost:5432/litellm_test' || '' }}
|
||||
run: |
|
||||
if [ "${WORKERS}" = "0" ]; then
|
||||
uv run --no-sync pytest ${TEST_PATH:?} \
|
||||
|
|
@ -143,7 +142,7 @@ jobs:
|
|||
-n "${WORKERS}" \
|
||||
--reruns "${RERUNS}" \
|
||||
--reruns-delay 1 \
|
||||
--dist=loadscope \
|
||||
--dist="${DIST}" \
|
||||
--durations=20 \
|
||||
--cov=litellm \
|
||||
--cov-report=xml:coverage.xml \
|
||||
|
|
|
|||
2
.github/workflows/check_duplicate_issues.yml
vendored
2
.github/workflows/check_duplicate_issues.yml
vendored
|
|
@ -39,7 +39,7 @@ jobs:
|
|||
if: github.event.action == 'opened'
|
||||
uses: actions/setup-python@a26af69be951a213d495a4c3e4e4022e16d87065 # v5.6.0
|
||||
with:
|
||||
python-version: "3.11"
|
||||
python-version: "3.12"
|
||||
|
||||
- name: Auto-close if high-confidence duplicate
|
||||
if: github.event.action == 'opened'
|
||||
|
|
|
|||
65
.github/workflows/create-release-branch.yml
vendored
Normal file
65
.github/workflows/create-release-branch.yml
vendored
Normal file
|
|
@ -0,0 +1,65 @@
|
|||
name: Create Release Branch
|
||||
|
||||
on:
|
||||
workflow_dispatch:
|
||||
inputs:
|
||||
tag:
|
||||
description: "Release tag (e.g. v1.83.0-stable) — branch will be named release/<tag>"
|
||||
required: true
|
||||
type: string
|
||||
commit_hash:
|
||||
description: "Full 40-char commit SHA the branch should point to"
|
||||
required: true
|
||||
type: string
|
||||
workflow_call:
|
||||
inputs:
|
||||
tag:
|
||||
description: "Release tag"
|
||||
required: true
|
||||
type: string
|
||||
commit_hash:
|
||||
description: "Full 40-char commit SHA the branch should point to"
|
||||
required: true
|
||||
type: string
|
||||
|
||||
permissions: {}
|
||||
|
||||
jobs:
|
||||
create-branch:
|
||||
name: Create Release Branch
|
||||
runs-on: ubuntu-latest
|
||||
permissions:
|
||||
contents: write
|
||||
steps:
|
||||
- name: Validate inputs
|
||||
env:
|
||||
TAG: ${{ inputs.tag }}
|
||||
COMMIT_HASH: ${{ inputs.commit_hash }}
|
||||
run: |
|
||||
if ! echo "${COMMIT_HASH}" | grep -qE '^[0-9a-f]{40}$'; then
|
||||
echo "::error::commit_hash must be a full 40-character commit SHA"
|
||||
exit 1
|
||||
fi
|
||||
if ! echo "${TAG}" | grep -qE '^v[0-9]+\.[0-9]+\.[0-9]+'; then
|
||||
echo "::error::tag must start with vX.Y.Z"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
- name: Create release branch
|
||||
env:
|
||||
TAG: ${{ inputs.tag }}
|
||||
COMMIT_HASH: ${{ inputs.commit_hash }}
|
||||
uses: actions/github-script@60a0d83039c74a4aee543508d2ffcb1c3799cdea # v7.0.1
|
||||
with:
|
||||
script: |
|
||||
const tag = process.env.TAG;
|
||||
const commitHash = process.env.COMMIT_HASH;
|
||||
const branchName = `release/${tag}`;
|
||||
|
||||
await github.rest.git.createRef({
|
||||
owner: context.repo.owner,
|
||||
repo: context.repo.repo,
|
||||
ref: `refs/heads/${branchName}`,
|
||||
sha: commitHash,
|
||||
});
|
||||
core.info(`Created branch ${branchName} at ${commitHash}`);
|
||||
11
.github/workflows/create-release.yml
vendored
11
.github/workflows/create-release.yml
vendored
|
|
@ -102,6 +102,17 @@ jobs:
|
|||
body: updatedBody,
|
||||
draft: false,
|
||||
});
|
||||
|
||||
} catch (error) {
|
||||
core.setFailed(error.message);
|
||||
}
|
||||
|
||||
create-branch:
|
||||
name: Create Release Branch
|
||||
needs: release
|
||||
permissions:
|
||||
contents: write
|
||||
uses: ./.github/workflows/create-release-branch.yml
|
||||
with:
|
||||
tag: ${{ inputs.tag }}
|
||||
commit_hash: ${{ inputs.commit_hash }}
|
||||
|
|
|
|||
|
|
@ -29,7 +29,7 @@ jobs:
|
|||
- name: Set up Python
|
||||
uses: actions/setup-python@a26af69be951a213d495a4c3e4e4022e16d87065 # v5.6.0
|
||||
with:
|
||||
python-version: "3.11"
|
||||
python-version: "3.12"
|
||||
|
||||
- name: Set up uv
|
||||
uses: astral-sh/setup-uv@37802adc94f370d6bfd71619e3f0bf239e1f3b78 # v7
|
||||
|
|
|
|||
2
.github/workflows/scan_duplicate_issues.yml
vendored
2
.github/workflows/scan_duplicate_issues.yml
vendored
|
|
@ -29,7 +29,7 @@ jobs:
|
|||
- name: Set up Python
|
||||
uses: actions/setup-python@a26af69be951a213d495a4c3e4e4022e16d87065 # v5.6.0
|
||||
with:
|
||||
python-version: "3.13"
|
||||
python-version: "3.12"
|
||||
|
||||
- name: Scan for duplicate issues
|
||||
env:
|
||||
|
|
|
|||
136
.github/workflows/test-code-quality.yml
vendored
Normal file
136
.github/workflows/test-code-quality.yml
vendored
Normal file
|
|
@ -0,0 +1,136 @@
|
|||
name: Code Quality Checks
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event.pull_request.number || github.ref }}
|
||||
cancel-in-progress: true
|
||||
|
||||
jobs:
|
||||
code-quality:
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 15
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955 # v4.3.0
|
||||
with:
|
||||
persist-credentials: false
|
||||
|
||||
- name: Checkout litellm-docs (for documentation_tests)
|
||||
uses: actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955 # v4.3.0
|
||||
with:
|
||||
repository: BerriAI/litellm-docs
|
||||
path: _litellm_docs_checkout
|
||||
persist-credentials: false
|
||||
|
||||
- name: Wire up docs path expected by documentation_tests/*
|
||||
run: |
|
||||
# documentation_tests scripts read from docs/my-website/docs/...
|
||||
# In litellm-docs the same files live at docs/... (repo root).
|
||||
# Point docs/my-website -> litellm-docs checkout so the paths resolve.
|
||||
rm -rf docs/my-website
|
||||
ln -s ../_litellm_docs_checkout docs/my-website
|
||||
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@a26af69be951a213d495a4c3e4e4022e16d87065 # v5.6.0
|
||||
with:
|
||||
python-version: "3.12"
|
||||
|
||||
- name: Set up uv
|
||||
uses: astral-sh/setup-uv@37802adc94f370d6bfd71619e3f0bf239e1f3b78 # v7
|
||||
with:
|
||||
version: "0.10.9"
|
||||
|
||||
- name: Cache uv dependencies
|
||||
uses: actions/cache@0057852bfaa89a56745cba8c7296529d2fc39830 # v4.3.0
|
||||
with:
|
||||
path: |
|
||||
~/.cache/uv
|
||||
.venv
|
||||
key: ${{ runner.os }}-uv-${{ hashFiles('uv.lock') }}
|
||||
restore-keys: |
|
||||
${{ runner.os }}-uv-
|
||||
|
||||
- name: Install dependencies
|
||||
run: uv sync --frozen --all-groups --all-extras
|
||||
|
||||
- name: check_licenses
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/check_licenses.py
|
||||
|
||||
- name: check_provider_folders_documented
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/check_provider_folders_documented.py
|
||||
|
||||
- name: router_code_coverage
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/router_code_coverage.py
|
||||
|
||||
- name: test_chat_completion_imports
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/test_chat_completion_imports.py
|
||||
|
||||
- name: info_log_check
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/info_log_check.py
|
||||
|
||||
- name: check_guardrail_apply_decorator
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/check_guardrail_apply_decorator.py
|
||||
|
||||
- name: test_ban_set_verbose
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/test_ban_set_verbose.py
|
||||
|
||||
- name: code_qa_check_tests
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/code_qa_check_tests.py
|
||||
|
||||
- name: check_get_model_cost_key_performance
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/check_get_model_cost_key_performance.py
|
||||
|
||||
- name: test_proxy_types_import
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/test_proxy_types_import.py
|
||||
|
||||
- name: callback_manager_test
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/callback_manager_test.py
|
||||
|
||||
- name: recursive_detector
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/recursive_detector.py
|
||||
|
||||
- name: test_router_strategy_async
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/test_router_strategy_async.py
|
||||
|
||||
- name: litellm_logging_code_coverage
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/litellm_logging_code_coverage.py
|
||||
|
||||
- name: ensure_async_clients_test
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/ensure_async_clients_test.py
|
||||
|
||||
- name: enforce_llms_folder_style
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/enforce_llms_folder_style.py
|
||||
|
||||
- name: prevent_key_leaks_in_exceptions
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/prevent_key_leaks_in_exceptions.py
|
||||
|
||||
- name: check_unsafe_enterprise_import
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/check_unsafe_enterprise_import.py
|
||||
|
||||
- name: ban_copy_deepcopy_kwargs
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/ban_copy_deepcopy_kwargs.py
|
||||
|
||||
- name: check_fastuuid_usage
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/check_fastuuid_usage.py
|
||||
|
||||
- name: memory_test
|
||||
run: uv run --no-sync python ./tests/code_coverage_tests/memory_test.py
|
||||
|
||||
- name: documentation_test_env_keys
|
||||
run: uv run --no-sync python ./tests/documentation_tests/test_env_keys.py
|
||||
|
||||
- name: documentation_test_router_settings
|
||||
run: uv run --no-sync python ./tests/documentation_tests/test_router_settings.py
|
||||
|
||||
- name: documentation_test_api_docs
|
||||
run: uv run --no-sync python ./tests/documentation_tests/test_api_docs.py
|
||||
39
.github/workflows/test-semgrep.yml
vendored
Normal file
39
.github/workflows/test-semgrep.yml
vendored
Normal file
|
|
@ -0,0 +1,39 @@
|
|||
name: Semgrep
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event.pull_request.number || github.ref }}
|
||||
cancel-in-progress: true
|
||||
|
||||
jobs:
|
||||
semgrep:
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 10
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955 # v4.3.0
|
||||
with:
|
||||
persist-credentials: false
|
||||
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@a26af69be951a213d495a4c3e4e4022e16d87065 # v5.6.0
|
||||
with:
|
||||
python-version: "3.12"
|
||||
|
||||
- name: Set up uv
|
||||
uses: astral-sh/setup-uv@37802adc94f370d6bfd71619e3f0bf239e1f3b78 # v7
|
||||
with:
|
||||
version: "0.10.9"
|
||||
|
||||
- name: Run Semgrep (custom rules)
|
||||
run: uv tool run --from 'semgrep==1.157.0' semgrep scan --config .semgrep/rules . --error
|
||||
38
.github/workflows/test-unit-caching-redis.yml
vendored
Normal file
38
.github/workflows/test-unit-caching-redis.yml
vendored
Normal file
|
|
@ -0,0 +1,38 @@
|
|||
name: "Unit Tests: Caching (Redis)"
|
||||
|
||||
# Uses cloud Redis credentials — only runs on trusted branches, not PRs.
|
||||
# This prevents external PRs from accessing Redis credentials.
|
||||
on:
|
||||
push:
|
||||
branches: [main, "litellm_*"]
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.ref }}
|
||||
cancel-in-progress: true
|
||||
|
||||
jobs:
|
||||
caching-redis:
|
||||
uses: ./.github/workflows/_test-unit-services-base.yml
|
||||
with:
|
||||
# Redis-only tests that do NOT require provider API keys.
|
||||
# Tests needing API keys (test_caching.py, test_caching_ssl.py, test_prometheus_service.py,
|
||||
# test_router_caching.py) are in Phase 3 integration workflows.
|
||||
test-path: >-
|
||||
tests/local_testing/test_dual_cache.py
|
||||
tests/local_testing/test_redis_batch_optimizations.py
|
||||
tests/local_testing/test_router_utils.py
|
||||
workers: 2
|
||||
reruns: 2
|
||||
timeout-minutes: 20
|
||||
enable-redis: true
|
||||
enable-postgres: false
|
||||
secrets:
|
||||
REDIS_HOST: ${{ secrets.REDIS_HOST }}
|
||||
REDIS_PORT: ${{ secrets.REDIS_PORT }}
|
||||
REDIS_PASSWORD: ${{ secrets.REDIS_PASSWORD }}
|
||||
DATABASE_URL: ${{ secrets.DATABASE_URL }}
|
||||
POSTGRES_USER: ${{ secrets.POSTGRES_USER }}
|
||||
POSTGRES_PASSWORD: ${{ secrets.POSTGRES_PASSWORD }}
|
||||
216
.github/workflows/test-unit-proxy-db.yml
vendored
216
.github/workflows/test-unit-proxy-db.yml
vendored
|
|
@ -12,8 +12,74 @@ concurrency:
|
|||
group: ${{ github.workflow }}-${{ github.ref }}
|
||||
cancel-in-progress: true
|
||||
|
||||
# Semantic matrix: each shard groups tests by concern (auth, server, logging, …)
|
||||
# rather than alphabetical letter ranges. Adding a new test file means adding it
|
||||
# to whichever group it belongs to, not reshuffling slices.
|
||||
#
|
||||
# Design targets:
|
||||
# * Every shard runs in <= 7 minutes of wall-clock on the default runner.
|
||||
# Most of a shard's time is pytest plugin load + xdist worker imports +
|
||||
# pytest-cov instrumentation, not the tests themselves. Keeping per-shard
|
||||
# work low and matching worker count to runner cores is what controls it.
|
||||
# * workers: 4 matches the 4-core ubuntu-latest runner. -n 8 on 4 cores
|
||||
# oversubscribes 2x and workers fight for CPU during their cold-start
|
||||
# imports (measured ~441% CPU for -n 8 locally, i.e. ~55% effective).
|
||||
# * test_key_generate_prisma.py stays serial (workers=0) — it has event-loop
|
||||
# conflicts with the logging worker when run in parallel.
|
||||
# * test_proxy_utils.py runs as a single shard with --dist=worksteal so
|
||||
# xdist balances its 188 parametrized cases across workers instead of
|
||||
# pinning the whole file to one worker (the default --dist=loadscope
|
||||
# behavior for single-file targets).
|
||||
# * test_db_schema_migration.py is isolated because one test in it
|
||||
# (test_aaaasschema_migration_check) takes ~170s — by itself it
|
||||
# determines the shard's wall-clock floor.
|
||||
jobs:
|
||||
# Fast guard — fails the workflow if a test_*.py file under
|
||||
# tests/proxy_unit_tests/ is not referenced by any matrix entry below.
|
||||
# The semantic-shard design (no catch-all "remaining" bucket) relies on
|
||||
# every test file being explicitly assigned; this guard prevents a new
|
||||
# file from silently dropping out of CI.
|
||||
assert-shard-coverage:
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 2
|
||||
permissions:
|
||||
contents: read
|
||||
steps:
|
||||
- uses: actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955 # v4.3.0
|
||||
with:
|
||||
persist-credentials: false
|
||||
- name: Assert every test_*.py is in a matrix shard
|
||||
run: |
|
||||
python3 - <<'PY'
|
||||
import pathlib, sys, yaml
|
||||
wf = yaml.safe_load(open(".github/workflows/test-unit-proxy-db.yml"))
|
||||
matrix = wf["jobs"]["proxy-db"]["strategy"]["matrix"]["include"]
|
||||
referenced = set()
|
||||
for entry in matrix:
|
||||
for token in entry["test-path"].split():
|
||||
if token.startswith("tests/proxy_unit_tests/"):
|
||||
referenced.add(pathlib.PurePosixPath(token).name)
|
||||
actual = {p.name for p in pathlib.Path("tests/proxy_unit_tests").iterdir()
|
||||
if p.name.startswith("test_") and (p.suffix == ".py" or p.is_dir())
|
||||
and p.name != "test_configs"}
|
||||
orphans = sorted(actual - referenced)
|
||||
if orphans:
|
||||
print("ERROR: the following files/dirs under tests/proxy_unit_tests/")
|
||||
print(" are not assigned to any shard in test-unit-proxy-db.yml:")
|
||||
for o in orphans:
|
||||
print(f" - {o}")
|
||||
print()
|
||||
print("Add each to whichever semantic shard it belongs to.")
|
||||
sys.exit(1)
|
||||
print(f"OK: all {len(actual)} files assigned to a shard.")
|
||||
PY
|
||||
|
||||
proxy-db:
|
||||
needs: assert-shard-coverage
|
||||
# Display only the semantic shard name in the checks UI instead of GHA's
|
||||
# default "proxy-db (key-generation, tests/proxy_unit_tests/…, 0, loadscope, 20)"
|
||||
# which includes every matrix field and gets truncated past the test-path.
|
||||
name: ${{ matrix.test-group }}
|
||||
permissions:
|
||||
contents: read
|
||||
id-token: write
|
||||
|
|
@ -22,19 +88,146 @@ jobs:
|
|||
fail-fast: false
|
||||
matrix:
|
||||
include:
|
||||
# Key generation tests must NOT run in parallel (event loop conflicts with logging worker)
|
||||
# Must run serially — event-loop conflict with the logging worker.
|
||||
- test-group: key-generation
|
||||
test-path: "tests/proxy_unit_tests/test_key_generate_prisma.py"
|
||||
workers: 0
|
||||
timeout: 30
|
||||
- test-group: auth-checks
|
||||
test-path: "tests/proxy_unit_tests/test_auth_checks.py tests/proxy_unit_tests/test_user_api_key_auth.py"
|
||||
workers: 8
|
||||
dist: loadscope
|
||||
timeout: 20
|
||||
- test-group: remaining
|
||||
test-path: "tests/proxy_unit_tests --ignore=tests/proxy_unit_tests/test_key_generate_prisma.py --ignore=tests/proxy_unit_tests/test_auth_checks.py --ignore=tests/proxy_unit_tests/test_user_api_key_auth.py"
|
||||
workers: 8
|
||||
timeout: 30
|
||||
|
||||
# ---- auth: split into 2 shards ----
|
||||
- test-group: auth-checks
|
||||
test-path: >-
|
||||
tests/proxy_unit_tests/test_auth_checks.py
|
||||
tests/proxy_unit_tests/test_user_api_key_auth.py
|
||||
workers: 4
|
||||
dist: loadscope
|
||||
timeout: 15
|
||||
- test-group: jwt-and-keys
|
||||
test-path: >-
|
||||
tests/proxy_unit_tests/test_jwt.py
|
||||
tests/proxy_unit_tests/test_jwt_key_mapping.py
|
||||
tests/proxy_unit_tests/test_proxy_custom_auth.py
|
||||
tests/proxy_unit_tests/test_key_generate_dynamodb.py
|
||||
tests/proxy_unit_tests/test_deployed_proxy_keygen.py
|
||||
workers: 4
|
||||
dist: loadscope
|
||||
timeout: 15
|
||||
|
||||
# ---- test_proxy_utils.py, single shard, worksteal distribution ----
|
||||
- test-group: proxy-utils
|
||||
test-path: "tests/proxy_unit_tests/test_proxy_utils.py"
|
||||
workers: 4
|
||||
dist: worksteal
|
||||
timeout: 15
|
||||
|
||||
# ---- proxy server: split into 2 shards ----
|
||||
- test-group: proxy-server-core
|
||||
test-path: >-
|
||||
tests/proxy_unit_tests/test_proxy_server.py
|
||||
tests/proxy_unit_tests/test_proxy_server_keys.py
|
||||
tests/proxy_unit_tests/test_proxy_server_caching.py
|
||||
tests/proxy_unit_tests/test_proxy_server_langfuse.py
|
||||
tests/proxy_unit_tests/test_proxy_server_spend.py
|
||||
tests/proxy_unit_tests/test_aproxy_startup.py
|
||||
workers: 4
|
||||
dist: loadscope
|
||||
timeout: 15
|
||||
- test-group: proxy-runtime
|
||||
test-path: >-
|
||||
tests/proxy_unit_tests/test_proxy_config_unit_test.py
|
||||
tests/proxy_unit_tests/test_proxy_routes.py
|
||||
tests/proxy_unit_tests/test_proxy_gunicorn.py
|
||||
tests/proxy_unit_tests/test_server_root_path.py
|
||||
tests/proxy_unit_tests/test_proxy_pass_user_config.py
|
||||
tests/proxy_unit_tests/test_proxy_token_counter.py
|
||||
workers: 4
|
||||
dist: loadscope
|
||||
timeout: 15
|
||||
|
||||
# ---- logging: split into 2 shards ----
|
||||
- test-group: custom-logging
|
||||
test-path: >-
|
||||
tests/proxy_unit_tests/test_custom_callback_input.py
|
||||
tests/proxy_unit_tests/test_custom_logger_s3_gcs.py
|
||||
tests/proxy_unit_tests/test_proxy_custom_logger.py
|
||||
workers: 4
|
||||
dist: loadscope
|
||||
timeout: 15
|
||||
- test-group: logging-misc
|
||||
test-path: >-
|
||||
tests/proxy_unit_tests/test_proxy_reject_logging.py
|
||||
tests/proxy_unit_tests/test_audit_logs_proxy.py
|
||||
tests/proxy_unit_tests/test_search_api_logging.py
|
||||
workers: 4
|
||||
dist: loadscope
|
||||
timeout: 15
|
||||
|
||||
# ---- db-and-spend: isolate the 170s schema-migration test ----
|
||||
# test_db_schema_migration.py has exactly one test, and that test
|
||||
# is mostly waiting on `prisma migrate deploy` / `prisma migrate
|
||||
# diff` subprocesses (~170s). It does no CPU-bound Python work
|
||||
# inside the test. Running with workers=0 (serial, no xdist)
|
||||
# skips the 4-worker cold-start cost we'd otherwise pay for a
|
||||
# single test, saving ~4 minutes of wall-clock.
|
||||
- test-group: schema-migration
|
||||
test-path: "tests/proxy_unit_tests/test_db_schema_migration.py"
|
||||
workers: 0
|
||||
dist: loadscope
|
||||
timeout: 15
|
||||
- test-group: db-and-spend
|
||||
test-path: >-
|
||||
tests/proxy_unit_tests/test_prisma_client_backoff_retry.py
|
||||
tests/proxy_unit_tests/test_db_schema_changes.py
|
||||
tests/proxy_unit_tests/test_e2e_pod_lock_manager.py
|
||||
tests/proxy_unit_tests/test_skills_db.py
|
||||
tests/proxy_unit_tests/test_update_daily_tag_spend.py
|
||||
tests/proxy_unit_tests/test_update_spend.py
|
||||
tests/proxy_unit_tests/test_project_endpoints_prisma.py
|
||||
tests/proxy_unit_tests/test_proxy_encrypt_decrypt.py
|
||||
workers: 4
|
||||
dist: loadscope
|
||||
timeout: 15
|
||||
|
||||
# ---- guardrails + budget + hooks: split into 2 ----
|
||||
- test-group: guardrails-hooks
|
||||
test-path: >-
|
||||
tests/proxy_unit_tests/test_proxy_setting_guardrails.py
|
||||
tests/proxy_unit_tests/test_banned_keyword_list.py
|
||||
tests/proxy_unit_tests/test_unit_test_proxy_hooks.py
|
||||
workers: 4
|
||||
dist: loadscope
|
||||
timeout: 15
|
||||
- test-group: budgets
|
||||
test-path: >-
|
||||
tests/proxy_unit_tests/test_default_end_user_budget_simple.py
|
||||
tests/proxy_unit_tests/test_unit_test_max_model_budget_limiter.py
|
||||
tests/proxy_unit_tests/test_zero_cost_model_budget_bypass.py
|
||||
workers: 4
|
||||
dist: loadscope
|
||||
timeout: 15
|
||||
|
||||
- test-group: endpoints-and-responses
|
||||
test-path: >-
|
||||
tests/proxy_unit_tests/test_blog_posts_endpoint.py
|
||||
tests/proxy_unit_tests/test_models_fallback_endpoint.py
|
||||
tests/proxy_unit_tests/test_google_endpoint_routing.py
|
||||
tests/proxy_unit_tests/test_google_gemini_proxy_request.py
|
||||
tests/proxy_unit_tests/test_get_favicon.py
|
||||
tests/proxy_unit_tests/test_get_image.py
|
||||
tests/proxy_unit_tests/test_ui_path_detection.py
|
||||
tests/proxy_unit_tests/test_prompt_test_endpoint.py
|
||||
tests/proxy_unit_tests/test_check_batch_cost.py
|
||||
tests/proxy_unit_tests/test_check_responses_cost.py
|
||||
tests/proxy_unit_tests/test_response_polling_handler.py
|
||||
tests/proxy_unit_tests/test_response_polling_pre_call_checks.py
|
||||
tests/proxy_unit_tests/test_realtime_cache.py
|
||||
tests/proxy_unit_tests/test_proxy_exception_mapping.py
|
||||
tests/proxy_unit_tests/test_custom_tokenizer_bug.py
|
||||
tests/proxy_unit_tests/test_model_response_typing
|
||||
workers: 4
|
||||
dist: loadscope
|
||||
timeout: 15
|
||||
uses: ./.github/workflows/_test-unit-services-base.yml
|
||||
with:
|
||||
test-path: ${{ matrix.test-path }}
|
||||
|
|
@ -42,8 +235,5 @@ jobs:
|
|||
reruns: 2
|
||||
timeout-minutes: ${{ matrix.timeout }}
|
||||
enable-postgres: true
|
||||
dist: ${{ matrix.dist }}
|
||||
artifact-name: proxy-db-${{ matrix.test-group }}
|
||||
secrets:
|
||||
DATABASE_URL: ${{ secrets.DATABASE_URL }}
|
||||
POSTGRES_USER: ${{ secrets.POSTGRES_USER }}
|
||||
POSTGRES_PASSWORD: ${{ secrets.POSTGRES_PASSWORD }}
|
||||
|
|
|
|||
|
|
@ -36,6 +36,8 @@ jobs:
|
|||
tests/test_litellm/proxy/health_endpoints
|
||||
tests/test_litellm/proxy/public_endpoints
|
||||
tests/test_litellm/proxy/prompts
|
||||
tests/test_litellm/proxy/rag_endpoints
|
||||
tests/test_litellm/proxy/realtime_endpoints
|
||||
tests/test_litellm/proxy/ui_crud_endpoints
|
||||
workers: 2
|
||||
reruns: 2
|
||||
|
|
|
|||
8
.github/workflows/test-unit-security.yml
vendored
8
.github/workflows/test-unit-security.yml
vendored
|
|
@ -1,6 +1,8 @@
|
|||
name: "Unit Tests: Security"
|
||||
|
||||
# Uses DATABASE_URL secret — only runs on trusted branches, not PRs.
|
||||
# Kept push-only (was previously required by DATABASE_URL secret scoping;
|
||||
# now the postgres credentials are ephemeral localhost values but the
|
||||
# push-trigger stays to match the proxy-db workflow cadence).
|
||||
on:
|
||||
push:
|
||||
branches: [main, "litellm_**"]
|
||||
|
|
@ -24,7 +26,3 @@ jobs:
|
|||
timeout-minutes: 20
|
||||
enable-postgres: true
|
||||
artifact-name: security
|
||||
secrets:
|
||||
DATABASE_URL: ${{ secrets.DATABASE_URL }}
|
||||
POSTGRES_USER: ${{ secrets.POSTGRES_USER }}
|
||||
POSTGRES_PASSWORD: ${{ secrets.POSTGRES_PASSWORD }}
|
||||
|
|
|
|||
|
|
@ -110,7 +110,7 @@ LiteLLM is a unified interface for 100+ LLM providers with two main components:
|
|||
- When wiring a new UI entity type to an existing backend endpoint, verify the backend API contract (single value vs. array, required vs. optional params) and ensure the UI controls match — e.g., use a single-select dropdown when the backend accepts a single value, not a multi-select
|
||||
|
||||
### UI Component Library
|
||||
- **Always use `antd` for new UI components** — we are migrating off of `@tremor/react`. Do not introduce new `Badge`, `Text`, `Card`, `Grid`, `Title`, or other imports from `@tremor/react` in any new or modified file. Use `antd` equivalents: `Tag` for labels, plain `<span>`/`<div>` with Tailwind classes (or `Typography.Text`) for text, `Card` from `antd`, etc. Note that `antd` has no `"yellow"` Tag color — use `"gold"` for amber/yellow.
|
||||
- **Always use `antd` for new UI components** — we are migrating off of `@tremor/react`. Do not introduce new `Badge`, `Text`, `Card`, `Grid`, `Title`, or other imports from `@tremor/react` in any new or modified file. Use `antd` equivalents: `Tag` for labels, `Typography.Text` / `Typography.Title` / `Typography.Paragraph` for textual content (avoid plain text-only `<span>`, `<p>`, `<h*>` when Typography fits), and `Card` from `antd`. Note that `antd` has no `"yellow"` Tag color — use `"gold"` for amber/yellow.
|
||||
|
||||
### MCP OAuth / OpenAPI Transport Mapping
|
||||
- `TRANSPORT.OPENAPI` is a UI-only concept. The backend only accepts `"http"`, `"sse"`, or `"stdio"`. Always map it to `"http"` before any API call (including pre-OAuth temp-session calls).
|
||||
|
|
|
|||
13
Dockerfile
13
Dockerfile
|
|
@ -27,10 +27,8 @@ RUN apk add --no-cache \
|
|||
npm \
|
||||
libsndfile
|
||||
|
||||
ENV PRISMA_BINARY_CACHE_DIR=/app/.cache/prisma-python/binaries \
|
||||
UV_PROJECT_ENVIRONMENT=/app/.venv \
|
||||
ENV UV_PROJECT_ENVIRONMENT=/app/.venv \
|
||||
UV_LINK_MODE=copy \
|
||||
XDG_CACHE_HOME=/app/.cache \
|
||||
PATH="/app/.venv/bin:${PATH}"
|
||||
|
||||
# Copy dependency metadata first for layer caching
|
||||
|
|
@ -94,11 +92,14 @@ RUN apk add --no-cache bash openssl tzdata nodejs npm python3 libsndfile supervi
|
|||
{ apk del --no-cache npm 2>/dev/null || true; }
|
||||
|
||||
WORKDIR /app
|
||||
ENV PRISMA_BINARY_CACHE_DIR=/app/.cache/prisma-python/binaries \
|
||||
XDG_CACHE_HOME=/app/.cache \
|
||||
PATH="/app/.venv/bin:${PATH}"
|
||||
ENV PATH="/app/.venv/bin:${PATH}"
|
||||
|
||||
COPY --from=builder /app /app
|
||||
# Prisma binaries live in $HOME/.cache (default prisma-python location),
|
||||
# which is /root/.cache here. Copy them from the builder so they survive
|
||||
# deployments that volume-mount /app/.cache (e.g. readOnlyRootFilesystem
|
||||
# + emptyDir) — otherwise the mount would shadow the baked-in query engine.
|
||||
COPY --from=builder /root/.cache /root/.cache
|
||||
|
||||
RUN find /app/.venv -type f -path "*/tornado/test/*" -delete && \
|
||||
find /app/.venv -type d -path "*/tornado/test" -delete
|
||||
|
|
|
|||
|
|
@ -1,23 +1,234 @@
|
|||
import argparse
|
||||
import os
|
||||
import subprocess
|
||||
from pathlib import Path
|
||||
from datetime import datetime
|
||||
import testing.postgresql
|
||||
import re
|
||||
import shutil
|
||||
import subprocess
|
||||
import sys
|
||||
from datetime import datetime
|
||||
from pathlib import Path
|
||||
|
||||
import testing.postgresql
|
||||
|
||||
|
||||
def create_migration(migration_name: str = None):
|
||||
DESTRUCTIVE_PATTERN = re.compile(r"\bDROP\s+(COLUMN|TABLE|INDEX)\b", re.IGNORECASE)
|
||||
DEFAULT_BASE_BRANCH = "litellm_internal_staging"
|
||||
|
||||
|
||||
def _find_destructive_statements(sql: str) -> list:
|
||||
"""Return SQL lines containing DROP COLUMN, DROP TABLE, or DROP INDEX."""
|
||||
return [
|
||||
line.strip() for line in sql.splitlines() if DESTRUCTIVE_PATTERN.search(line)
|
||||
]
|
||||
|
||||
|
||||
def _print_freshness_failure(
|
||||
base_branch: str, reason: str, stderr_text: str = ""
|
||||
) -> None:
|
||||
"""Loudly refuse to run when the freshness check can't be completed."""
|
||||
banner = "=" * 72
|
||||
out = sys.stderr
|
||||
print(banner, file=out)
|
||||
print(f" FRESHNESS CHECK FAILED — COULD NOT VERIFY origin/{base_branch}", file=out)
|
||||
print(banner, file=out)
|
||||
print("", file=out)
|
||||
print(f"Reason: {reason}", file=out)
|
||||
if stderr_text:
|
||||
print("", file=out)
|
||||
print("git stderr:", file=out)
|
||||
for line in stderr_text.rstrip().splitlines():
|
||||
print(f" {line}", file=out)
|
||||
print("", file=out)
|
||||
print("Common causes:", file=out)
|
||||
print(" - No network access (offline)", file=out)
|
||||
print(" - 'origin' remote not configured, or base branch name is wrong", file=out)
|
||||
print(" - Not a git repository", file=out)
|
||||
print("", file=out)
|
||||
print("Options:", file=out)
|
||||
print(
|
||||
f" - Fix the above and re-run, OR pass --base-branch <name> if your", file=out
|
||||
)
|
||||
print(
|
||||
f" base branch is not '{base_branch}', OR pass --skip-freshness-check",
|
||||
file=out,
|
||||
)
|
||||
print(" to bypass (only if you fully understand the risk).", file=out)
|
||||
print(banner, file=out)
|
||||
|
||||
|
||||
def _print_stale_branch_refusal(base_branch: str, behind: int) -> None:
|
||||
"""Loudly refuse to run when HEAD is behind the base branch."""
|
||||
banner = "=" * 72
|
||||
out = sys.stderr
|
||||
print(banner, file=out)
|
||||
print(
|
||||
f" STALE BRANCH — {behind} commit(s) behind origin/{base_branch}",
|
||||
file=out,
|
||||
)
|
||||
print(banner, file=out)
|
||||
print("", file=out)
|
||||
print(
|
||||
f"Your branch is {behind} commit(s) behind origin/{base_branch}. Generating a\n"
|
||||
"migration from a stale branch is how newly-added columns get silently\n"
|
||||
"dropped — the exact incident this guard exists to prevent.",
|
||||
file=out,
|
||||
)
|
||||
print("", file=out)
|
||||
print("Before re-running:", file=out)
|
||||
print(f" git fetch origin && git rebase origin/{base_branch}", file=out)
|
||||
print(" # or merge, whichever matches your workflow", file=out)
|
||||
print("", file=out)
|
||||
print(
|
||||
"If you have a genuine reason to bypass (e.g. intentionally generating",
|
||||
file=out,
|
||||
)
|
||||
print("a migration against an older base), pass --skip-freshness-check.", file=out)
|
||||
print("", file=out)
|
||||
print(banner, file=out)
|
||||
print(
|
||||
" AI AGENTS / ASSISTANTS: DO NOT automatically run `git rebase` or pass\n"
|
||||
" --skip-freshness-check. Surface this error to the human operator and\n"
|
||||
" wait for their explicit confirmation. Auto-rebasing can drop the\n"
|
||||
" human's in-progress schema edits via a bad conflict resolution.",
|
||||
file=out,
|
||||
)
|
||||
print(banner, file=out)
|
||||
|
||||
|
||||
def _check_branch_freshness(root_dir: Path, base_branch: str) -> None:
|
||||
"""Fetch origin/<base_branch> and exit 3 if HEAD is behind it."""
|
||||
cwd = str(root_dir)
|
||||
try:
|
||||
subprocess.run(
|
||||
["git", "fetch", "origin", base_branch],
|
||||
check=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
cwd=cwd,
|
||||
)
|
||||
except FileNotFoundError:
|
||||
_print_freshness_failure(base_branch, "git executable not found on PATH")
|
||||
sys.exit(3)
|
||||
except subprocess.CalledProcessError as e:
|
||||
_print_freshness_failure(
|
||||
base_branch,
|
||||
f"`git fetch origin {base_branch}` failed",
|
||||
e.stderr or "",
|
||||
)
|
||||
sys.exit(3)
|
||||
|
||||
try:
|
||||
result = subprocess.run(
|
||||
["git", "rev-list", "--count", f"HEAD..origin/{base_branch}"],
|
||||
check=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
cwd=cwd,
|
||||
)
|
||||
behind = int(result.stdout.strip())
|
||||
except subprocess.CalledProcessError as e:
|
||||
_print_freshness_failure(
|
||||
base_branch,
|
||||
f"`git rev-list HEAD..origin/{base_branch}` failed",
|
||||
e.stderr or "",
|
||||
)
|
||||
sys.exit(3)
|
||||
except ValueError:
|
||||
_print_freshness_failure(
|
||||
base_branch,
|
||||
"could not parse commit count from `git rev-list`",
|
||||
)
|
||||
sys.exit(3)
|
||||
|
||||
if behind > 0:
|
||||
_print_stale_branch_refusal(base_branch, behind)
|
||||
sys.exit(3)
|
||||
|
||||
print(f"Branch freshness OK: up to date with origin/{base_branch}.")
|
||||
|
||||
|
||||
def _print_destructive_refusal(destructive_lines: list) -> None:
|
||||
"""Loudly refuse to write a destructive migration and explain how to proceed."""
|
||||
banner = "=" * 72
|
||||
out = sys.stderr
|
||||
print(banner, file=out)
|
||||
print(
|
||||
" DESTRUCTIVE MIGRATION DETECTED — REFUSING TO WRITE MIGRATION FILE", file=out
|
||||
)
|
||||
print(banner, file=out)
|
||||
print("", file=out)
|
||||
print(
|
||||
"The generated migration contains the following destructive statements:",
|
||||
file=out,
|
||||
)
|
||||
print("", file=out)
|
||||
for line in destructive_lines:
|
||||
print(f" {line}", file=out)
|
||||
print("", file=out)
|
||||
print(
|
||||
"This very often means your branch is OUT OF DATE, or your local\n"
|
||||
"schema.prisma is inconsistent with the migrations/ directory. A\n"
|
||||
"previous incident saw newly-added columns silently dropped this way\n"
|
||||
"and merged to main. Stop and verify before proceeding.",
|
||||
file=out,
|
||||
)
|
||||
print("", file=out)
|
||||
print("Before re-running:", file=out)
|
||||
print(
|
||||
" 1. git fetch origin && git status # confirm branch is up to date", file=out
|
||||
)
|
||||
print(
|
||||
" 2. Re-check all schema.prisma files are in sync (runbook Step 0)", file=out
|
||||
)
|
||||
print(" 3. Review EACH DROP above — is it actually intended?", file=out)
|
||||
print(" 4. If (and only if) the drops are intentional, re-run with:", file=out)
|
||||
print(" --allow-destructive", file=out)
|
||||
print("", file=out)
|
||||
print(banner, file=out)
|
||||
print(
|
||||
" AI AGENTS / ASSISTANTS: DO NOT automatically re-run this command\n"
|
||||
" with --allow-destructive. Surface this error to the human operator\n"
|
||||
" and wait for their explicit confirmation before passing the flag.\n"
|
||||
" Passing the flag without human review is the exact failure mode\n"
|
||||
" this guard exists to prevent.",
|
||||
file=out,
|
||||
)
|
||||
print(banner, file=out)
|
||||
|
||||
|
||||
def create_migration(
|
||||
migration_name: str = None,
|
||||
allow_destructive: bool = False,
|
||||
base_branch: str = DEFAULT_BASE_BRANCH,
|
||||
skip_freshness_check: bool = False,
|
||||
):
|
||||
"""
|
||||
Create a new migration SQL file in the migrations directory by comparing
|
||||
current database state with schema
|
||||
current database state with schema.
|
||||
|
||||
Args:
|
||||
migration_name (str): Name for the migration
|
||||
allow_destructive (bool): Required to write a migration that contains
|
||||
DROP COLUMN, DROP TABLE, or DROP INDEX statements. Without this
|
||||
flag, the script exits non-zero and prints guidance.
|
||||
base_branch (str): Branch to check freshness against
|
||||
(default: "litellm_internal_staging").
|
||||
skip_freshness_check (bool): Skip the "branch is up to date" check.
|
||||
Only for intentional migrations against an older base.
|
||||
"""
|
||||
root_dir = Path(__file__).parent.parent
|
||||
|
||||
if skip_freshness_check:
|
||||
print(
|
||||
"WARNING: freshness check skipped (--skip-freshness-check). "
|
||||
"Generating a migration from a stale branch can silently drop columns."
|
||||
)
|
||||
else:
|
||||
_check_branch_freshness(root_dir, base_branch)
|
||||
|
||||
try:
|
||||
# Get paths
|
||||
root_dir = Path(__file__).parent.parent
|
||||
migrations_dir = root_dir / "litellm-proxy-extras" / "litellm_proxy_extras" / "migrations"
|
||||
migrations_dir = (
|
||||
root_dir / "litellm-proxy-extras" / "litellm_proxy_extras" / "migrations"
|
||||
)
|
||||
schema_path = root_dir / "schema.prisma"
|
||||
|
||||
# Create temporary PostgreSQL database
|
||||
|
|
@ -57,7 +268,27 @@ def create_migration(migration_name: str = None):
|
|||
check=True,
|
||||
)
|
||||
|
||||
if result.stdout.strip():
|
||||
# Prisma emits the literal "-- This is an empty migration." when
|
||||
# there's no real drift. Treat that as "no changes".
|
||||
diff_sql = result.stdout
|
||||
stripped = diff_sql.strip()
|
||||
is_empty_diff = (
|
||||
not stripped or stripped == "-- This is an empty migration."
|
||||
)
|
||||
|
||||
if not is_empty_diff:
|
||||
destructive_lines = _find_destructive_statements(diff_sql)
|
||||
if destructive_lines and not allow_destructive:
|
||||
_print_destructive_refusal(destructive_lines)
|
||||
sys.exit(2)
|
||||
if destructive_lines and allow_destructive:
|
||||
print(
|
||||
"WARNING: writing destructive migration "
|
||||
"(--allow-destructive passed). Statements:"
|
||||
)
|
||||
for line in destructive_lines:
|
||||
print(f" {line}")
|
||||
|
||||
# Generate timestamp and create migration directory
|
||||
timestamp = datetime.now().strftime("%Y%m%d%H%M%S")
|
||||
migration_name = migration_name or "unnamed_migration"
|
||||
|
|
@ -66,7 +297,7 @@ def create_migration(migration_name: str = None):
|
|||
|
||||
# Write the SQL to migration.sql
|
||||
migration_file = migration_dir / "migration.sql"
|
||||
migration_file.write_text(result.stdout)
|
||||
migration_file.write_text(diff_sql)
|
||||
|
||||
print(f"Created migration in {migration_dir}")
|
||||
return True
|
||||
|
|
@ -88,8 +319,48 @@ def create_migration(migration_name: str = None):
|
|||
|
||||
|
||||
if __name__ == "__main__":
|
||||
# If running directly, can optionally pass migration name as argument
|
||||
import sys
|
||||
|
||||
migration_name = sys.argv[1] if len(sys.argv) > 1 else None
|
||||
create_migration(migration_name)
|
||||
parser = argparse.ArgumentParser(
|
||||
description=(
|
||||
"Generate a Prisma migration by diffing the temp DB "
|
||||
"(existing migrations applied) against schema.prisma."
|
||||
)
|
||||
)
|
||||
parser.add_argument(
|
||||
"migration_name",
|
||||
nargs="?",
|
||||
default=None,
|
||||
help="Name for the migration (used in the generated directory name).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--allow-destructive",
|
||||
action="store_true",
|
||||
help=(
|
||||
"Required to write a migration that contains DROP COLUMN, "
|
||||
"DROP TABLE, or DROP INDEX. Without this flag, destructive "
|
||||
"diffs are refused."
|
||||
),
|
||||
)
|
||||
parser.add_argument(
|
||||
"--base-branch",
|
||||
default=DEFAULT_BASE_BRANCH,
|
||||
help=(
|
||||
f"Branch to check freshness against (default: {DEFAULT_BASE_BRANCH}). "
|
||||
"The script fetches origin/<base-branch> and refuses to run if HEAD "
|
||||
"is behind it."
|
||||
),
|
||||
)
|
||||
parser.add_argument(
|
||||
"--skip-freshness-check",
|
||||
action="store_true",
|
||||
help=(
|
||||
"Bypass the 'branch is up to date' check. Only for intentional "
|
||||
"migrations against an older base. Pairs poorly with automation."
|
||||
),
|
||||
)
|
||||
args = parser.parse_args()
|
||||
create_migration(
|
||||
args.migration_name,
|
||||
allow_destructive=args.allow_destructive,
|
||||
base_branch=args.base_branch,
|
||||
skip_freshness_check=args.skip_freshness_check,
|
||||
)
|
||||
|
|
|
|||
|
|
@ -24,24 +24,26 @@ async def interactive_chat_with_mcp():
|
|||
Interactive CLI chat with the agent and MCP server
|
||||
"""
|
||||
config = Config()
|
||||
|
||||
|
||||
# Configure Anthropic SDK to point to LiteLLM gateway
|
||||
litellm_base_url = setup_litellm_env(config)
|
||||
|
||||
|
||||
# Fetch available models from proxy
|
||||
available_models = await fetch_available_models(litellm_base_url, config.LITELLM_API_KEY)
|
||||
|
||||
available_models = await fetch_available_models(
|
||||
litellm_base_url, config.LITELLM_API_KEY
|
||||
)
|
||||
|
||||
current_model = config.LITELLM_MODEL
|
||||
|
||||
|
||||
# MCP server configuration
|
||||
mcp_server_url = f"{litellm_base_url}/mcp/deepwiki2"
|
||||
use_mcp = os.getenv("USE_MCP", "true").lower() == "true"
|
||||
|
||||
|
||||
if not use_mcp:
|
||||
print("⚠️ MCP disabled via USE_MCP=false")
|
||||
|
||||
|
||||
print_header(litellm_base_url, current_model, has_mcp=use_mcp)
|
||||
|
||||
|
||||
while True:
|
||||
# Configure agent options
|
||||
if use_mcp:
|
||||
|
|
@ -58,7 +60,7 @@ async def interactive_chat_with_mcp():
|
|||
"url": mcp_server_url,
|
||||
"headers": {
|
||||
"Authorization": f"Bearer {config.LITELLM_API_KEY}"
|
||||
}
|
||||
},
|
||||
}
|
||||
},
|
||||
)
|
||||
|
|
@ -78,12 +80,12 @@ async def interactive_chat_with_mcp():
|
|||
model=current_model,
|
||||
max_turns=50,
|
||||
)
|
||||
|
||||
|
||||
# Create agent client
|
||||
try:
|
||||
async with ClaudeSDKClient(options=options) as client:
|
||||
conversation_active = True
|
||||
|
||||
|
||||
while conversation_active:
|
||||
# Get user input
|
||||
try:
|
||||
|
|
@ -91,34 +93,36 @@ async def interactive_chat_with_mcp():
|
|||
except (EOFError, KeyboardInterrupt):
|
||||
print("\n\n👋 Goodbye!")
|
||||
return
|
||||
|
||||
|
||||
# Handle commands
|
||||
if user_input.lower() in ['quit', 'exit']:
|
||||
if user_input.lower() in ["quit", "exit"]:
|
||||
print("\n👋 Goodbye!")
|
||||
return
|
||||
|
||||
if user_input.lower() == 'clear':
|
||||
|
||||
if user_input.lower() == "clear":
|
||||
print("\n🔄 Starting new conversation...\n")
|
||||
conversation_active = False
|
||||
continue
|
||||
|
||||
if user_input.lower() == 'models':
|
||||
|
||||
if user_input.lower() == "models":
|
||||
handle_model_list(available_models, current_model)
|
||||
continue
|
||||
|
||||
if user_input.lower() == 'model':
|
||||
new_model, should_restart = handle_model_switch(available_models, current_model)
|
||||
|
||||
if user_input.lower() == "model":
|
||||
new_model, should_restart = handle_model_switch(
|
||||
available_models, current_model
|
||||
)
|
||||
if should_restart:
|
||||
current_model = new_model
|
||||
conversation_active = False
|
||||
continue
|
||||
|
||||
|
||||
if not user_input:
|
||||
continue
|
||||
|
||||
|
||||
# Stream response from agent
|
||||
await stream_response(client, user_input)
|
||||
|
||||
|
||||
except Exception as e:
|
||||
print(f"\n❌ Error creating agent client: {e}")
|
||||
print("This might be an MCP configuration issue. Try running without MCP:")
|
||||
|
|
|
|||
|
|
@ -8,13 +8,13 @@ import httpx
|
|||
|
||||
class Config:
|
||||
"""Configuration for LiteLLM Gateway connection"""
|
||||
|
||||
|
||||
# LiteLLM proxy URL (default to local instance)
|
||||
LITELLM_PROXY_URL = os.getenv("LITELLM_PROXY_URL", "http://localhost:4000")
|
||||
|
||||
|
||||
# LiteLLM API key (master key or virtual key)
|
||||
LITELLM_API_KEY = os.getenv("LITELLM_API_KEY", "sk-1234")
|
||||
|
||||
|
||||
# Model name as configured in LiteLLM (e.g., "bedrock-claude-sonnet-4", "gpt-4", etc.)
|
||||
LITELLM_MODEL = os.getenv("LITELLM_MODEL", "bedrock-claude-sonnet-4.5")
|
||||
|
||||
|
|
@ -28,7 +28,7 @@ async def fetch_available_models(base_url: str, api_key: str) -> list[str]:
|
|||
response = await client.get(
|
||||
f"{base_url}/models",
|
||||
headers={"Authorization": f"Bearer {api_key}"},
|
||||
timeout=10.0
|
||||
timeout=10.0,
|
||||
)
|
||||
response.raise_for_status()
|
||||
data = response.json()
|
||||
|
|
@ -50,7 +50,7 @@ def setup_litellm_env(config: Config):
|
|||
"""
|
||||
Configure environment variables to point Agent SDK to LiteLLM
|
||||
"""
|
||||
litellm_base_url = config.LITELLM_PROXY_URL.rstrip('/')
|
||||
litellm_base_url = config.LITELLM_PROXY_URL.rstrip("/")
|
||||
os.environ["ANTHROPIC_BASE_URL"] = litellm_base_url
|
||||
os.environ["ANTHROPIC_API_KEY"] = config.LITELLM_API_KEY
|
||||
return litellm_base_url
|
||||
|
|
@ -87,10 +87,12 @@ def handle_model_list(available_models: list[str], current_model: str):
|
|||
print(f" {marker} {i}. {model}")
|
||||
|
||||
|
||||
def handle_model_switch(available_models: list[str], current_model: str) -> tuple[str, bool]:
|
||||
def handle_model_switch(
|
||||
available_models: list[str], current_model: str
|
||||
) -> tuple[str, bool]:
|
||||
"""
|
||||
Handle model switching
|
||||
|
||||
|
||||
Returns:
|
||||
tuple: (new_model, should_restart_conversation)
|
||||
"""
|
||||
|
|
@ -98,7 +100,7 @@ def handle_model_switch(available_models: list[str], current_model: str) -> tupl
|
|||
for i, model in enumerate(available_models, 1):
|
||||
marker = "✓" if model == current_model else " "
|
||||
print(f" {marker} {i}. {model}")
|
||||
|
||||
|
||||
try:
|
||||
choice = input("\nEnter number (or press Enter to cancel): ").strip()
|
||||
if choice:
|
||||
|
|
@ -112,7 +114,7 @@ def handle_model_switch(available_models: list[str], current_model: str) -> tupl
|
|||
print("❌ Invalid choice")
|
||||
except (ValueError, IndexError):
|
||||
print("❌ Invalid input")
|
||||
|
||||
|
||||
return current_model, False
|
||||
|
||||
|
||||
|
|
@ -120,41 +122,43 @@ async def stream_response(client, user_input: str):
|
|||
"""
|
||||
Stream response from the agent
|
||||
"""
|
||||
print("\n🤖 Assistant: ", end='', flush=True)
|
||||
|
||||
print("\n🤖 Assistant: ", end="", flush=True)
|
||||
|
||||
try:
|
||||
await client.query(user_input)
|
||||
|
||||
|
||||
# Show loading indicator
|
||||
print("⏳ thinking...", end='', flush=True)
|
||||
|
||||
print("⏳ thinking...", end="", flush=True)
|
||||
|
||||
# Stream the response
|
||||
first_chunk = True
|
||||
async for msg in client.receive_response():
|
||||
# Clear loading indicator on first message
|
||||
if first_chunk:
|
||||
print("\r🤖 Assistant: ", end='', flush=True)
|
||||
print("\r🤖 Assistant: ", end="", flush=True)
|
||||
first_chunk = False
|
||||
|
||||
|
||||
# Handle different message types
|
||||
if hasattr(msg, 'type'):
|
||||
if msg.type == 'content_block_delta':
|
||||
if hasattr(msg, "type"):
|
||||
if msg.type == "content_block_delta":
|
||||
# Streaming text delta
|
||||
if hasattr(msg, 'delta') and hasattr(msg.delta, 'text'):
|
||||
print(msg.delta.text, end='', flush=True)
|
||||
elif msg.type == 'content_block_start':
|
||||
if hasattr(msg, "delta") and hasattr(msg.delta, "text"):
|
||||
print(msg.delta.text, end="", flush=True)
|
||||
elif msg.type == "content_block_start":
|
||||
# Start of content block
|
||||
if hasattr(msg, 'content_block') and hasattr(msg.content_block, 'text'):
|
||||
print(msg.content_block.text, end='', flush=True)
|
||||
|
||||
if hasattr(msg, "content_block") and hasattr(
|
||||
msg.content_block, "text"
|
||||
):
|
||||
print(msg.content_block.text, end="", flush=True)
|
||||
|
||||
# Fallback to original content handling
|
||||
if hasattr(msg, 'content'):
|
||||
if hasattr(msg, "content"):
|
||||
for content_block in msg.content:
|
||||
if hasattr(content_block, 'text'):
|
||||
print(content_block.text, end='', flush=True)
|
||||
|
||||
if hasattr(content_block, "text"):
|
||||
print(content_block.text, end="", flush=True)
|
||||
|
||||
print() # New line after response
|
||||
|
||||
|
||||
except Exception as e:
|
||||
print(f"\r\n❌ Error: {e}")
|
||||
print("Please check your LiteLLM gateway is running and configured correctly.")
|
||||
|
|
|
|||
|
|
@ -24,17 +24,19 @@ async def interactive_chat():
|
|||
Interactive CLI chat with the agent
|
||||
"""
|
||||
config = Config()
|
||||
|
||||
|
||||
# Configure Anthropic SDK to point to LiteLLM gateway
|
||||
litellm_base_url = setup_litellm_env(config)
|
||||
|
||||
|
||||
# Fetch available models from proxy
|
||||
available_models = await fetch_available_models(litellm_base_url, config.LITELLM_API_KEY)
|
||||
|
||||
available_models = await fetch_available_models(
|
||||
litellm_base_url, config.LITELLM_API_KEY
|
||||
)
|
||||
|
||||
current_model = config.LITELLM_MODEL
|
||||
|
||||
|
||||
print_header(litellm_base_url, current_model)
|
||||
|
||||
|
||||
while True:
|
||||
# Configure agent options for each conversation
|
||||
options = ClaudeAgentOptions(
|
||||
|
|
@ -42,11 +44,11 @@ async def interactive_chat():
|
|||
model=current_model,
|
||||
max_turns=50,
|
||||
)
|
||||
|
||||
|
||||
# Create agent client
|
||||
async with ClaudeSDKClient(options=options) as client:
|
||||
conversation_active = True
|
||||
|
||||
|
||||
while conversation_active:
|
||||
# Get user input
|
||||
try:
|
||||
|
|
@ -54,31 +56,33 @@ async def interactive_chat():
|
|||
except (EOFError, KeyboardInterrupt):
|
||||
print("\n\n👋 Goodbye!")
|
||||
return
|
||||
|
||||
|
||||
# Handle commands
|
||||
if user_input.lower() in ['quit', 'exit']:
|
||||
if user_input.lower() in ["quit", "exit"]:
|
||||
print("\n👋 Goodbye!")
|
||||
return
|
||||
|
||||
if user_input.lower() == 'clear':
|
||||
|
||||
if user_input.lower() == "clear":
|
||||
print("\n🔄 Starting new conversation...\n")
|
||||
conversation_active = False
|
||||
continue
|
||||
|
||||
if user_input.lower() == 'models':
|
||||
|
||||
if user_input.lower() == "models":
|
||||
handle_model_list(available_models, current_model)
|
||||
continue
|
||||
|
||||
if user_input.lower() == 'model':
|
||||
new_model, should_restart = handle_model_switch(available_models, current_model)
|
||||
|
||||
if user_input.lower() == "model":
|
||||
new_model, should_restart = handle_model_switch(
|
||||
available_models, current_model
|
||||
)
|
||||
if should_restart:
|
||||
current_model = new_model
|
||||
conversation_active = False
|
||||
continue
|
||||
|
||||
|
||||
if not user_input:
|
||||
continue
|
||||
|
||||
|
||||
# Stream response from agent
|
||||
await stream_response(client, user_input)
|
||||
|
||||
|
|
|
|||
|
|
@ -11,15 +11,15 @@ BEDROCK_BATCH_MODEL = "bedrock/batch-anthropic.claude-3-5-sonnet-20240620-v1:0"
|
|||
batch_input_file = client.files.create(
|
||||
file=open("./bedrock_batch_completions.jsonl", "rb"),
|
||||
purpose="batch",
|
||||
extra_body={"target_model_names": BEDROCK_BATCH_MODEL}
|
||||
extra_body={"target_model_names": BEDROCK_BATCH_MODEL},
|
||||
)
|
||||
print(batch_input_file)
|
||||
|
||||
# Create batch
|
||||
batch = client.batches.create(
|
||||
batch = client.batches.create(
|
||||
input_file_id=batch_input_file.id,
|
||||
endpoint="/v1/chat/completions",
|
||||
completion_window="24h",
|
||||
metadata={"description": "Test batch job"},
|
||||
)
|
||||
print(batch)
|
||||
print(batch)
|
||||
|
|
|
|||
|
|
@ -8,6 +8,7 @@ in your Python scripts after running `litellm-proxy login`.
|
|||
|
||||
from textwrap import indent
|
||||
import litellm
|
||||
|
||||
LITELLM_BASE_URL = "http://localhost:4000/"
|
||||
|
||||
|
||||
|
|
@ -15,38 +16,38 @@ def main():
|
|||
"""Using CLI token with LiteLLM SDK"""
|
||||
print("🚀 Using CLI Token with LiteLLM SDK")
|
||||
print("=" * 40)
|
||||
#litellm._turn_on_debug()
|
||||
|
||||
# litellm._turn_on_debug()
|
||||
|
||||
# Get the CLI token
|
||||
api_key = litellm.get_litellm_gateway_api_key()
|
||||
|
||||
|
||||
if not api_key:
|
||||
print("❌ No CLI token found. Please run 'litellm-proxy login' first.")
|
||||
return
|
||||
|
||||
|
||||
print("✅ Found CLI token.")
|
||||
|
||||
available_models = litellm.get_valid_models(
|
||||
check_provider_endpoint=True,
|
||||
custom_llm_provider="litellm_proxy",
|
||||
api_key=api_key,
|
||||
api_base=LITELLM_BASE_URL
|
||||
api_base=LITELLM_BASE_URL,
|
||||
)
|
||||
|
||||
|
||||
print("✅ Available models:")
|
||||
if available_models:
|
||||
for i, model in enumerate(available_models, 1):
|
||||
print(f" {i:2d}. {model}")
|
||||
else:
|
||||
print(" No models available")
|
||||
|
||||
|
||||
# Use with LiteLLM
|
||||
try:
|
||||
response = litellm.completion(
|
||||
model="litellm_proxy/gemini/gemini-2.5-flash",
|
||||
messages=[{"role": "user", "content": "Hello from CLI token!"}],
|
||||
api_key=api_key,
|
||||
base_url=LITELLM_BASE_URL
|
||||
base_url=LITELLM_BASE_URL,
|
||||
)
|
||||
print(f"✅ LLM Response: {response.model_dump_json(indent=4)}")
|
||||
except Exception as e:
|
||||
|
|
@ -55,7 +56,7 @@ def main():
|
|||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
|
||||
|
||||
print("\n💡 Tips:")
|
||||
print("1. Run 'litellm-proxy login' to authenticate first")
|
||||
print("2. Replace 'https://your-proxy.com' with your actual proxy URL")
|
||||
|
|
|
|||
|
|
@ -3,11 +3,12 @@ Use LiteLLM Proxy MCP Gateway to call MCP tools.
|
|||
|
||||
When using LiteLLM Proxy, you can use the same MCP tools across all your LLM providers.
|
||||
"""
|
||||
|
||||
import openai
|
||||
|
||||
client = openai.OpenAI(
|
||||
api_key="sk-1234", # paste your litellm proxy api key here
|
||||
base_url="http://localhost:4000" # paste your litellm proxy base url here
|
||||
api_key="sk-1234", # paste your litellm proxy api key here
|
||||
base_url="http://localhost:4000", # paste your litellm proxy base url here
|
||||
)
|
||||
print("Making API request to Responses API with MCP tools")
|
||||
|
||||
|
|
@ -17,7 +18,7 @@ response = client.responses.create(
|
|||
{
|
||||
"role": "user",
|
||||
"content": "give me TLDR of what BerriAI/litellm repo is about",
|
||||
"type": "message"
|
||||
"type": "message",
|
||||
}
|
||||
],
|
||||
tools=[
|
||||
|
|
@ -25,11 +26,11 @@ response = client.responses.create(
|
|||
"type": "mcp",
|
||||
"server_label": "litellm",
|
||||
"server_url": "litellm_proxy",
|
||||
"require_approval": "never"
|
||||
"require_approval": "never",
|
||||
}
|
||||
],
|
||||
stream=True,
|
||||
tool_choice="required"
|
||||
tool_choice="required",
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
|
|
|
|||
|
|
@ -40,8 +40,10 @@ class InMemorySecretManager(CustomSecretManager):
|
|||
) -> Optional[str]:
|
||||
"""Read secret synchronously"""
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
|
||||
verbose_proxy_logger.info(f"CUSTOM SECRET MANAGER: LOOKING FOR SECRET: {secret_name}")
|
||||
|
||||
verbose_proxy_logger.info(
|
||||
f"CUSTOM SECRET MANAGER: LOOKING FOR SECRET: {secret_name}"
|
||||
)
|
||||
value = self.secrets.get(secret_name)
|
||||
verbose_proxy_logger.info(f"CUSTOM SECRET MANAGER: READ SECRET: {value}")
|
||||
return value
|
||||
|
|
@ -76,4 +78,3 @@ class InMemorySecretManager(CustomSecretManager):
|
|||
del self.secrets[secret_name]
|
||||
return {"status": "deleted", "secret_name": secret_name}
|
||||
return {"status": "not_found", "secret_name": secret_name}
|
||||
|
||||
|
|
|
|||
|
|
@ -5,6 +5,7 @@ This example shows how to use LiveKit's xAI realtime plugin through LiteLLM prox
|
|||
LiteLLM acts as a unified interface, allowing you to switch between xAI, OpenAI,
|
||||
and Azure realtime APIs without changing your agent code.
|
||||
"""
|
||||
|
||||
import asyncio
|
||||
import json
|
||||
import os
|
||||
|
|
@ -23,71 +24,79 @@ async def run_voice_agent():
|
|||
2. Sends a user message
|
||||
3. Streams back the response
|
||||
"""
|
||||
|
||||
|
||||
url = f"ws://{PROXY_URL.replace('http://', '').replace('https://', '')}/v1/realtime?model={MODEL}"
|
||||
headers = {"Authorization": f"Bearer {API_KEY}"}
|
||||
|
||||
|
||||
print(f"🎙️ Connecting to voice agent...")
|
||||
print(f" Model: {MODEL}")
|
||||
print(f" Proxy: {PROXY_URL}")
|
||||
print()
|
||||
|
||||
|
||||
async with websockets.connect(url, additional_headers=headers) as ws:
|
||||
# Receive initial connection event
|
||||
initial = json.loads(await ws.recv())
|
||||
print(f"✅ Connected! Event: {initial['type']}\n")
|
||||
|
||||
|
||||
# Get user input
|
||||
user_message = input("💬 Your message: ").strip()
|
||||
if not user_message:
|
||||
user_message = "Tell me a fun fact about AI!"
|
||||
|
||||
|
||||
print(f"\n🤖 Sending to {MODEL}...\n")
|
||||
|
||||
|
||||
# Send user message
|
||||
await ws.send(json.dumps({
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{"type": "input_text", "text": user_message}]
|
||||
}
|
||||
}))
|
||||
|
||||
await ws.send(
|
||||
json.dumps(
|
||||
{
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{"type": "input_text", "text": user_message}],
|
||||
},
|
||||
}
|
||||
)
|
||||
)
|
||||
|
||||
# Request response
|
||||
await ws.send(json.dumps({
|
||||
"type": "response.create",
|
||||
"response": {"modalities": ["text", "audio"]}
|
||||
}))
|
||||
|
||||
await ws.send(
|
||||
json.dumps(
|
||||
{
|
||||
"type": "response.create",
|
||||
"response": {"modalities": ["text", "audio"]},
|
||||
}
|
||||
)
|
||||
)
|
||||
|
||||
# Stream response
|
||||
print("🎤 Response: ", end='', flush=True)
|
||||
print("🎤 Response: ", end="", flush=True)
|
||||
transcript = []
|
||||
|
||||
|
||||
try:
|
||||
while True:
|
||||
msg = await asyncio.wait_for(ws.recv(), timeout=15.0)
|
||||
event = json.loads(msg)
|
||||
|
||||
|
||||
# Capture transcript deltas
|
||||
if event['type'] == 'response.output_audio_transcript.delta':
|
||||
delta = event.get('delta', '')
|
||||
if event["type"] == "response.output_audio_transcript.delta":
|
||||
delta = event.get("delta", "")
|
||||
if delta:
|
||||
print(delta, end='', flush=True)
|
||||
print(delta, end="", flush=True)
|
||||
transcript.append(delta)
|
||||
|
||||
|
||||
# Done when response completes
|
||||
elif event['type'] == 'response.done':
|
||||
elif event["type"] == "response.done":
|
||||
break
|
||||
|
||||
|
||||
except asyncio.TimeoutError:
|
||||
pass
|
||||
|
||||
|
||||
print("\n")
|
||||
|
||||
|
||||
if transcript:
|
||||
print(f"✅ Complete response: {''.join(transcript)}")
|
||||
|
||||
|
||||
await ws.close()
|
||||
|
||||
|
||||
|
|
@ -97,7 +106,7 @@ def main():
|
|||
print("LiveKit xAI Voice Agent via LiteLLM Proxy")
|
||||
print("=" * 70)
|
||||
print()
|
||||
|
||||
|
||||
try:
|
||||
asyncio.run(run_voice_agent())
|
||||
except KeyboardInterrupt:
|
||||
|
|
|
|||
|
|
@ -1,10 +1,9 @@
|
|||
import base64
|
||||
from openai import OpenAI
|
||||
import time
|
||||
client = OpenAI(
|
||||
base_url="http://0.0.0.0:4001",
|
||||
api_key="sk-1234"
|
||||
)
|
||||
|
||||
client = OpenAI(base_url="http://0.0.0.0:4001", api_key="sk-1234")
|
||||
|
||||
|
||||
# Function to encode the image
|
||||
def encode_image(image_path):
|
||||
|
|
@ -25,7 +24,7 @@ response = client.responses.create(
|
|||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{ "type": "input_text", "text": "what color is the image"},
|
||||
{"type": "input_text", "text": "what color is the image"},
|
||||
{
|
||||
"type": "input_image",
|
||||
"image_url": f"data:image/jpeg;base64,{base64_image}",
|
||||
|
|
@ -36,7 +35,6 @@ response = client.responses.create(
|
|||
)
|
||||
|
||||
|
||||
|
||||
print(response.output_text)
|
||||
print("response1 id===", response.id)
|
||||
print("sleeping for 20 seconds...")
|
||||
|
|
@ -45,9 +43,7 @@ print("making follow up request for existing id")
|
|||
response2 = client.responses.create(
|
||||
model="bedrock/us.anthropic.claude-haiku-4-5-20251001-v1:0",
|
||||
previous_response_id=response.id,
|
||||
input="ok, and what objects are in the image?"
|
||||
input="ok, and what objects are in the image?",
|
||||
)
|
||||
|
||||
print(response2.output_text)
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -52,11 +52,11 @@ class RealtimeClient:
|
|||
async def connect(self):
|
||||
"""Connect to LiteLLM proxy realtime endpoint."""
|
||||
print(f"Connecting to {self.url}...")
|
||||
|
||||
|
||||
headers = {}
|
||||
if self.api_key:
|
||||
headers["Authorization"] = f"Bearer {self.api_key}"
|
||||
|
||||
|
||||
self.ws = await websockets.connect(
|
||||
self.url,
|
||||
additional_headers=headers,
|
||||
|
|
@ -175,7 +175,9 @@ class RealtimeClient:
|
|||
|
||||
try:
|
||||
while self.is_active:
|
||||
audio_data = self.input_stream.read(CHUNK_SIZE, exception_on_overflow=False)
|
||||
audio_data = self.input_stream.read(
|
||||
CHUNK_SIZE, exception_on_overflow=False
|
||||
)
|
||||
await self.send_audio_chunk(audio_data)
|
||||
await asyncio.sleep(0.01) # Small delay to prevent overwhelming
|
||||
except Exception as e:
|
||||
|
|
@ -270,6 +272,7 @@ async def main():
|
|||
except Exception as e:
|
||||
print(f"\n❌ Error: {e}")
|
||||
import traceback
|
||||
|
||||
traceback.print_exc()
|
||||
finally:
|
||||
await client.close()
|
||||
|
|
@ -281,7 +284,7 @@ if __name__ == "__main__":
|
|||
print("2. Bedrock is configured in proxy_server_config.yaml")
|
||||
print("3. AWS credentials are set")
|
||||
print()
|
||||
|
||||
|
||||
try:
|
||||
asyncio.run(main())
|
||||
except KeyboardInterrupt:
|
||||
|
|
|
|||
|
|
@ -21,49 +21,45 @@ from typing import Optional
|
|||
|
||||
class VeoVideoGenerator:
|
||||
"""Complete Veo video generation client using LiteLLM proxy."""
|
||||
|
||||
def __init__(self, base_url: str = "http://localhost:4000/gemini/v1beta",
|
||||
api_key: str = "sk-1234"):
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
base_url: str = "http://localhost:4000/gemini/v1beta",
|
||||
api_key: str = "sk-1234",
|
||||
):
|
||||
"""
|
||||
Initialize the Veo video generator.
|
||||
|
||||
|
||||
Args:
|
||||
base_url: Base URL for the LiteLLM proxy with Gemini pass-through
|
||||
api_key: API key for LiteLLM proxy authentication
|
||||
"""
|
||||
self.base_url = base_url
|
||||
self.api_key = api_key
|
||||
self.headers = {
|
||||
"x-goog-api-key": api_key,
|
||||
"Content-Type": "application/json"
|
||||
}
|
||||
|
||||
self.headers = {"x-goog-api-key": api_key, "Content-Type": "application/json"}
|
||||
|
||||
def generate_video(self, prompt: str) -> Optional[str]:
|
||||
"""
|
||||
Initiate video generation with Veo.
|
||||
|
||||
|
||||
Args:
|
||||
prompt: Text description of the video to generate
|
||||
|
||||
|
||||
Returns:
|
||||
Operation name if successful, None otherwise
|
||||
"""
|
||||
print(f"🎬 Generating video with prompt: '{prompt}'")
|
||||
|
||||
|
||||
url = f"{self.base_url}/models/veo-3.0-generate-preview:predictLongRunning"
|
||||
payload = {
|
||||
"instances": [{
|
||||
"prompt": prompt
|
||||
}]
|
||||
}
|
||||
|
||||
payload = {"instances": [{"prompt": prompt}]}
|
||||
|
||||
try:
|
||||
response = requests.post(url, headers=self.headers, json=payload)
|
||||
response.raise_for_status()
|
||||
|
||||
|
||||
data = response.json()
|
||||
operation_name = data.get("name")
|
||||
|
||||
|
||||
if operation_name:
|
||||
print(f"✅ Video generation started: {operation_name}")
|
||||
return operation_name
|
||||
|
|
@ -71,58 +67,64 @@ class VeoVideoGenerator:
|
|||
print("❌ No operation name returned")
|
||||
print(f"Response: {json.dumps(data, indent=2)}")
|
||||
return None
|
||||
|
||||
|
||||
except requests.RequestException as e:
|
||||
print(f"❌ Failed to start video generation: {e}")
|
||||
if hasattr(e, 'response') and e.response is not None:
|
||||
if hasattr(e, "response") and e.response is not None:
|
||||
try:
|
||||
error_data = e.response.json()
|
||||
print(f"Error details: {json.dumps(error_data, indent=2)}")
|
||||
except:
|
||||
print(f"Error response: {e.response.text}")
|
||||
return None
|
||||
|
||||
def wait_for_completion(self, operation_name: str, max_wait_time: int = 600) -> Optional[str]:
|
||||
|
||||
def wait_for_completion(
|
||||
self, operation_name: str, max_wait_time: int = 600
|
||||
) -> Optional[str]:
|
||||
"""
|
||||
Poll operation status until video generation is complete.
|
||||
|
||||
|
||||
Args:
|
||||
operation_name: Name of the operation to monitor
|
||||
max_wait_time: Maximum time to wait in seconds (default: 10 minutes)
|
||||
|
||||
|
||||
Returns:
|
||||
Video URI if successful, None otherwise
|
||||
"""
|
||||
print("⏳ Waiting for video generation to complete...")
|
||||
|
||||
|
||||
operation_url = f"{self.base_url}/{operation_name}"
|
||||
start_time = time.time()
|
||||
poll_interval = 10 # Start with 10 seconds
|
||||
|
||||
|
||||
while time.time() - start_time < max_wait_time:
|
||||
try:
|
||||
print(f"🔍 Polling status... ({int(time.time() - start_time)}s elapsed)")
|
||||
|
||||
print(
|
||||
f"🔍 Polling status... ({int(time.time() - start_time)}s elapsed)"
|
||||
)
|
||||
|
||||
response = requests.get(operation_url, headers=self.headers)
|
||||
response.raise_for_status()
|
||||
|
||||
|
||||
data = response.json()
|
||||
|
||||
|
||||
# Check for errors
|
||||
if "error" in data:
|
||||
print("❌ Error in video generation:")
|
||||
print(json.dumps(data["error"], indent=2))
|
||||
return None
|
||||
|
||||
|
||||
# Check if operation is complete
|
||||
is_done = data.get("done", False)
|
||||
|
||||
|
||||
if is_done:
|
||||
print("🎉 Video generation complete!")
|
||||
|
||||
|
||||
try:
|
||||
# Extract video URI from nested response
|
||||
video_uri = data["response"]["generateVideoResponse"]["generatedSamples"][0]["video"]["uri"]
|
||||
video_uri = data["response"]["generateVideoResponse"][
|
||||
"generatedSamples"
|
||||
][0]["video"]["uri"]
|
||||
print(f"📹 Video URI: {video_uri}")
|
||||
return video_uri
|
||||
except KeyError as e:
|
||||
|
|
@ -130,64 +132,68 @@ class VeoVideoGenerator:
|
|||
print("Full response:")
|
||||
print(json.dumps(data, indent=2))
|
||||
return None
|
||||
|
||||
|
||||
# Wait before next poll, with exponential backoff
|
||||
time.sleep(poll_interval)
|
||||
poll_interval = min(poll_interval * 1.2, 30) # Cap at 30 seconds
|
||||
|
||||
|
||||
except requests.RequestException as e:
|
||||
print(f"❌ Error polling operation status: {e}")
|
||||
time.sleep(poll_interval)
|
||||
|
||||
|
||||
print(f"⏰ Timeout after {max_wait_time} seconds")
|
||||
return None
|
||||
|
||||
def download_video(self, video_uri: str, output_filename: str = "generated_video.mp4") -> bool:
|
||||
|
||||
def download_video(
|
||||
self, video_uri: str, output_filename: str = "generated_video.mp4"
|
||||
) -> bool:
|
||||
"""
|
||||
Download the generated video file.
|
||||
|
||||
|
||||
Args:
|
||||
video_uri: URI of the video to download (from Google's response)
|
||||
output_filename: Local filename to save the video
|
||||
|
||||
|
||||
Returns:
|
||||
True if download successful, False otherwise
|
||||
"""
|
||||
print(f"⬇️ Downloading video...")
|
||||
print(f"Original URI: {video_uri}")
|
||||
|
||||
|
||||
# Convert Google URI to LiteLLM proxy URI
|
||||
# Example: files/abc123 -> /gemini/v1beta/files/abc123:download?alt=media
|
||||
if video_uri.startswith("files/"):
|
||||
download_path = f"{video_uri}:download?alt=media"
|
||||
else:
|
||||
download_path = video_uri
|
||||
|
||||
|
||||
litellm_download_url = f"{self.base_url}/{download_path}"
|
||||
print(f"Download URL: {litellm_download_url}")
|
||||
|
||||
|
||||
try:
|
||||
# Download with streaming and redirect handling
|
||||
response = requests.get(
|
||||
litellm_download_url,
|
||||
headers=self.headers,
|
||||
litellm_download_url,
|
||||
headers=self.headers,
|
||||
stream=True,
|
||||
allow_redirects=True # Handle redirects automatically
|
||||
allow_redirects=True, # Handle redirects automatically
|
||||
)
|
||||
response.raise_for_status()
|
||||
|
||||
|
||||
# Save video file
|
||||
with open(output_filename, 'wb') as f:
|
||||
with open(output_filename, "wb") as f:
|
||||
downloaded_size = 0
|
||||
for chunk in response.iter_content(chunk_size=8192):
|
||||
if chunk:
|
||||
f.write(chunk)
|
||||
downloaded_size += len(chunk)
|
||||
|
||||
|
||||
# Progress indicator for large files
|
||||
if downloaded_size % (1024 * 1024) == 0: # Every MB
|
||||
print(f"📦 Downloaded {downloaded_size / (1024*1024):.1f} MB...")
|
||||
|
||||
print(
|
||||
f"📦 Downloaded {downloaded_size / (1024*1024):.1f} MB..."
|
||||
)
|
||||
|
||||
# Verify file was created and has content
|
||||
if os.path.exists(output_filename):
|
||||
file_size = os.path.getsize(output_filename)
|
||||
|
|
@ -203,48 +209,52 @@ class VeoVideoGenerator:
|
|||
else:
|
||||
print("❌ File was not created")
|
||||
return False
|
||||
|
||||
|
||||
except requests.RequestException as e:
|
||||
print(f"❌ Download failed: {e}")
|
||||
if hasattr(e, 'response') and e.response is not None:
|
||||
if hasattr(e, "response") and e.response is not None:
|
||||
print(f"Status code: {e.response.status_code}")
|
||||
print(f"Response headers: {dict(e.response.headers)}")
|
||||
return False
|
||||
|
||||
|
||||
def generate_and_download(self, prompt: str, output_filename: str = None) -> bool:
|
||||
"""
|
||||
Complete workflow: generate video and download it.
|
||||
|
||||
|
||||
Args:
|
||||
prompt: Text description for video generation
|
||||
output_filename: Output filename (auto-generated if None)
|
||||
|
||||
|
||||
Returns:
|
||||
True if successful, False otherwise
|
||||
"""
|
||||
# Auto-generate filename if not provided
|
||||
if output_filename is None:
|
||||
timestamp = int(time.time())
|
||||
safe_prompt = "".join(c for c in prompt[:30] if c.isalnum() or c in (' ', '-', '_')).rstrip()
|
||||
output_filename = f"veo_video_{safe_prompt.replace(' ', '_')}_{timestamp}.mp4"
|
||||
|
||||
safe_prompt = "".join(
|
||||
c for c in prompt[:30] if c.isalnum() or c in (" ", "-", "_")
|
||||
).rstrip()
|
||||
output_filename = (
|
||||
f"veo_video_{safe_prompt.replace(' ', '_')}_{timestamp}.mp4"
|
||||
)
|
||||
|
||||
print("=" * 60)
|
||||
print("🎬 VEO VIDEO GENERATION WORKFLOW")
|
||||
print("=" * 60)
|
||||
|
||||
|
||||
# Step 1: Generate video
|
||||
operation_name = self.generate_video(prompt)
|
||||
if not operation_name:
|
||||
return False
|
||||
|
||||
|
||||
# Step 2: Wait for completion
|
||||
video_uri = self.wait_for_completion(operation_name)
|
||||
if not video_uri:
|
||||
return False
|
||||
|
||||
|
||||
# Step 3: Download video
|
||||
success = self.download_video(video_uri, output_filename)
|
||||
|
||||
|
||||
if success:
|
||||
print("=" * 60)
|
||||
print("🎉 SUCCESS! Video generation complete!")
|
||||
|
|
@ -254,51 +264,51 @@ class VeoVideoGenerator:
|
|||
print("=" * 60)
|
||||
print("❌ FAILED! Video generation or download failed")
|
||||
print("=" * 60)
|
||||
|
||||
|
||||
return success
|
||||
|
||||
|
||||
def main():
|
||||
"""
|
||||
Example usage of the VeoVideoGenerator.
|
||||
|
||||
|
||||
Configure these environment variables:
|
||||
- LITELLM_BASE_URL: Your LiteLLM proxy URL (default: http://localhost:4000/gemini/v1beta)
|
||||
- LITELLM_API_KEY: Your LiteLLM API key (default: sk-1234)
|
||||
"""
|
||||
|
||||
|
||||
# Configuration from environment or defaults
|
||||
base_url = os.getenv("LITELLM_BASE_URL", "http://localhost:4000/gemini/v1beta")
|
||||
api_key = os.getenv("LITELLM_API_KEY", "sk-1234")
|
||||
|
||||
|
||||
print("🚀 Starting Veo Video Generation Example")
|
||||
print(f"📡 Using LiteLLM proxy at: {base_url}")
|
||||
|
||||
|
||||
# Initialize generator
|
||||
generator = VeoVideoGenerator(base_url=base_url, api_key=api_key)
|
||||
|
||||
|
||||
# Example prompts - try different ones!
|
||||
example_prompts = [
|
||||
"A cat playing with a ball of yarn in a sunny garden",
|
||||
"Ocean waves crashing against rocky cliffs at sunset",
|
||||
"A bustling city street with people walking and cars passing by",
|
||||
"A peaceful forest with sunlight filtering through the trees"
|
||||
"A peaceful forest with sunlight filtering through the trees",
|
||||
]
|
||||
|
||||
|
||||
# Use first example or get from user
|
||||
prompt = example_prompts[0]
|
||||
print(f"🎬 Using prompt: '{prompt}'")
|
||||
|
||||
|
||||
# Generate and download video
|
||||
success = generator.generate_and_download(prompt)
|
||||
|
||||
|
||||
if success:
|
||||
print("\n✅ Example completed successfully!")
|
||||
print("💡 Try modifying the prompt in the script for different videos!")
|
||||
else:
|
||||
print("\n❌ Example failed!")
|
||||
print("🔧 Check your LiteLLM proxy configuration and Google AI Studio API key")
|
||||
|
||||
|
||||
# Troubleshooting tips
|
||||
print("\n🔍 Troubleshooting:")
|
||||
print("1. Ensure LiteLLM proxy is running with Google AI Studio pass-through")
|
||||
|
|
|
|||
|
|
@ -47,7 +47,7 @@ spec:
|
|||
{{- toYaml .Values.podSecurityContext | nindent 8 }}
|
||||
{{- with .Values.extraInitContainers }}
|
||||
initContainers:
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- tpl (toYaml .) $ | nindent 8 }}
|
||||
{{- end }}
|
||||
containers:
|
||||
- name: {{ include "litellm.name" . }}
|
||||
|
|
@ -212,7 +212,7 @@ spec:
|
|||
{{- toYaml . | nindent 12 }}
|
||||
{{- end }}
|
||||
{{- with .Values.extraContainers }}
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- tpl (toYaml .) $ | nindent 8 }}
|
||||
{{- end }}
|
||||
volumes:
|
||||
{{ if .Values.securityContext.readOnlyRootFilesystem }}
|
||||
|
|
|
|||
|
|
@ -37,7 +37,7 @@ spec:
|
|||
serviceAccountName: {{ include "litellm.migrationServiceAccountName" . }}
|
||||
{{- with .Values.migrationJob.extraInitContainers }}
|
||||
initContainers:
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- tpl (toYaml .) $ | nindent 8 }}
|
||||
{{- end }}
|
||||
containers:
|
||||
- name: prisma-migrations
|
||||
|
|
@ -96,7 +96,7 @@ spec:
|
|||
{{- toYaml . | nindent 12 }}
|
||||
{{- end }}
|
||||
{{- with .Values.migrationJob.extraContainers }}
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- tpl (toYaml .) $ | nindent 8 }}
|
||||
{{- end }}
|
||||
{{- with .Values.volumes }}
|
||||
volumes:
|
||||
|
|
|
|||
|
|
@ -319,3 +319,61 @@ tests:
|
|||
asserts:
|
||||
- notExists:
|
||||
path: spec.minReadySeconds
|
||||
- it: should work with extraInitContainers
|
||||
template: deployment.yaml
|
||||
set:
|
||||
extraInitContainers:
|
||||
- name: init-test
|
||||
image: busybox:latest
|
||||
command: ["echo", "hello"]
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.initContainers
|
||||
content:
|
||||
name: init-test
|
||||
image: busybox:latest
|
||||
command: ["echo", "hello"]
|
||||
- it: should support tpl in extraInitContainers
|
||||
template: deployment.yaml
|
||||
set:
|
||||
image:
|
||||
repository: ghcr.io/berriai/litellm-database
|
||||
tag: test
|
||||
extraInitContainers:
|
||||
- name: init-tpl
|
||||
image: "{{ .Values.image.repository }}:{{ .Values.image.tag }}"
|
||||
command: ["echo", "hello"]
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.initContainers
|
||||
content:
|
||||
name: init-tpl
|
||||
image: "ghcr.io/berriai/litellm-database:test"
|
||||
command: ["echo", "hello"]
|
||||
- it: should work with extraContainers
|
||||
template: deployment.yaml
|
||||
set:
|
||||
extraContainers:
|
||||
- name: sidecar
|
||||
image: busybox:latest
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.containers
|
||||
content:
|
||||
name: sidecar
|
||||
image: busybox:latest
|
||||
- it: should support tpl in extraContainers
|
||||
template: deployment.yaml
|
||||
set:
|
||||
image:
|
||||
repository: ghcr.io/berriai/litellm-database
|
||||
tag: test
|
||||
extraContainers:
|
||||
- name: sidecar-tpl
|
||||
image: "{{ .Values.image.repository }}:{{ .Values.image.tag }}"
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.containers
|
||||
content:
|
||||
name: sidecar-tpl
|
||||
image: "ghcr.io/berriai/litellm-database:test"
|
||||
|
|
|
|||
|
|
@ -188,3 +188,69 @@ tests:
|
|||
- equal:
|
||||
path: spec.template.spec.serviceAccountName
|
||||
value: pre-existing-sa
|
||||
- it: should work with extraInitContainers
|
||||
template: migrations-job.yaml
|
||||
set:
|
||||
migrationJob:
|
||||
enabled: true
|
||||
extraInitContainers:
|
||||
- name: init-test
|
||||
image: busybox:latest
|
||||
command: ["echo", "hello"]
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.initContainers
|
||||
content:
|
||||
name: init-test
|
||||
image: busybox:latest
|
||||
command: ["echo", "hello"]
|
||||
- it: should support tpl in extraInitContainers
|
||||
template: migrations-job.yaml
|
||||
set:
|
||||
image:
|
||||
repository: ghcr.io/berriai/litellm-database
|
||||
tag: test
|
||||
migrationJob:
|
||||
enabled: true
|
||||
extraInitContainers:
|
||||
- name: init-tpl
|
||||
image: "{{ .Values.image.repository }}:{{ .Values.image.tag }}"
|
||||
command: ["echo", "hello"]
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.initContainers
|
||||
content:
|
||||
name: init-tpl
|
||||
image: "ghcr.io/berriai/litellm-database:test"
|
||||
command: ["echo", "hello"]
|
||||
- it: should work with extraContainers
|
||||
template: migrations-job.yaml
|
||||
set:
|
||||
migrationJob:
|
||||
enabled: true
|
||||
extraContainers:
|
||||
- name: sidecar
|
||||
image: busybox:latest
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.containers
|
||||
content:
|
||||
name: sidecar
|
||||
image: busybox:latest
|
||||
- it: should support tpl in extraContainers
|
||||
template: migrations-job.yaml
|
||||
set:
|
||||
image:
|
||||
repository: ghcr.io/berriai/litellm-database
|
||||
tag: test
|
||||
migrationJob:
|
||||
enabled: true
|
||||
extraContainers:
|
||||
- name: sidecar-tpl
|
||||
image: "{{ .Values.image.repository }}:{{ .Values.image.tag }}"
|
||||
asserts:
|
||||
- contains:
|
||||
path: spec.template.spec.containers
|
||||
content:
|
||||
name: sidecar-tpl
|
||||
image: "ghcr.io/berriai/litellm-database:test"
|
||||
|
|
|
|||
|
|
@ -26,10 +26,8 @@ RUN apk add --no-cache \
|
|||
npm \
|
||||
libsndfile
|
||||
|
||||
ENV PRISMA_BINARY_CACHE_DIR=/app/.cache/prisma-python/binaries \
|
||||
UV_PROJECT_ENVIRONMENT=/app/.venv \
|
||||
ENV UV_PROJECT_ENVIRONMENT=/app/.venv \
|
||||
UV_LINK_MODE=copy \
|
||||
XDG_CACHE_HOME=/app/.cache \
|
||||
PATH="/app/.venv/bin:${PATH}"
|
||||
|
||||
# Copy dependency metadata first for layer caching
|
||||
|
|
@ -92,11 +90,14 @@ RUN apk add --no-cache bash openssl tzdata nodejs npm python3 libsndfile supervi
|
|||
{ apk del --no-cache npm 2>/dev/null || true; }
|
||||
|
||||
WORKDIR /app
|
||||
ENV PRISMA_BINARY_CACHE_DIR=/app/.cache/prisma-python/binaries \
|
||||
XDG_CACHE_HOME=/app/.cache \
|
||||
PATH="/app/.venv/bin:${PATH}"
|
||||
ENV PATH="/app/.venv/bin:${PATH}"
|
||||
|
||||
COPY --from=builder /app /app
|
||||
# Prisma binaries live in $HOME/.cache (default prisma-python location),
|
||||
# which is /root/.cache here. Copy them from the builder so they survive
|
||||
# deployments that volume-mount /app/.cache (e.g. readOnlyRootFilesystem
|
||||
# + emptyDir) — otherwise the mount would shadow the baked-in query engine.
|
||||
COPY --from=builder /root/.cache /root/.cache
|
||||
|
||||
RUN find /app/.venv -type f -path "*/tornado/test/*" -delete && \
|
||||
find /app/.venv -type d -path "*/tornado/test" -delete
|
||||
|
|
|
|||
|
|
@ -15,29 +15,21 @@ COPY --from=uvbin /uv /usr/local/bin/uv
|
|||
COPY --from=uvbin /uvx /usr/local/bin/uvx
|
||||
|
||||
RUN for i in 1 2 3; do \
|
||||
apk add --no-cache \
|
||||
python3 \
|
||||
python3-dev \
|
||||
clang \
|
||||
llvm \
|
||||
lld \
|
||||
gcc \
|
||||
linux-headers \
|
||||
build-base \
|
||||
bash \
|
||||
coreutils \
|
||||
curl \
|
||||
openssl \
|
||||
openssl-dev \
|
||||
nodejs \
|
||||
npm \
|
||||
libsndfile && break || sleep 5; \
|
||||
apk add --no-cache \
|
||||
python3 \
|
||||
python3-dev \
|
||||
gcc \
|
||||
bash \
|
||||
coreutils \
|
||||
curl \
|
||||
openssl \
|
||||
libsndfile \
|
||||
nodejs && break || sleep 5; \
|
||||
done
|
||||
|
||||
ENV UV_PROJECT_ENVIRONMENT=/app/.venv \
|
||||
UV_LINK_MODE=copy \
|
||||
NVM_DIR=/root/.nvm \
|
||||
PATH="/root/.nvm/versions/node/v20.20.2/bin:/app/.venv/bin:${PATH}" \
|
||||
PATH="/app/.venv/bin:${PATH}" \
|
||||
LITELLM_NON_ROOT=true \
|
||||
PRISMA_BINARY_CACHE_DIR=/app/.cache/prisma-python/binaries \
|
||||
PRISMA_CLI_BINARY_TARGETS="debian-openssl-3.0.x" \
|
||||
|
|
@ -49,7 +41,8 @@ COPY enterprise/pyproject.toml enterprise/
|
|||
COPY litellm-proxy-extras/pyproject.toml litellm-proxy-extras/
|
||||
|
||||
# Install third-party dependencies (cached unless pyproject.toml/uv.lock change)
|
||||
RUN uv sync --frozen --no-install-project --no-install-workspace --no-default-groups --no-editable \
|
||||
RUN --mount=type=cache,target=/app/.cache/uv,id=litellm-uv-cache \
|
||||
uv sync --frozen --no-install-project --no-install-workspace --no-default-groups --no-editable \
|
||||
--extra proxy \
|
||||
--extra proxy-runtime \
|
||||
--extra extra_proxy \
|
||||
|
|
@ -62,38 +55,12 @@ COPY . .
|
|||
# Set non-root flag for build time consistency
|
||||
ENV LITELLM_NON_ROOT=true
|
||||
|
||||
# Build Admin UI once and stage the static output for the runtime image.
|
||||
# NOTE: .npmrc files (which may set ignore-scripts=true and min-release-age=3d)
|
||||
# are temporarily renamed during npm install/ci so they don't block lifecycle
|
||||
# scripts needed by the build. This is safe because npm ci installs from
|
||||
# package-lock.json with pinned versions + integrity hashes.
|
||||
# Stage the pre-built Admin UI from the checked-in Next.js static export.
|
||||
# _experimental/out/ is regenerated as part of the release runbook.
|
||||
# Restructure extensionless routes (foo.html -> foo/index.html) to match the layout
|
||||
# proxy_server.py expects, and drop a readiness marker.
|
||||
RUN mkdir -p /var/lib/litellm/ui /var/lib/litellm/assets && \
|
||||
([ -f /app/.npmrc ] && mv /app/.npmrc /app/.npmrc.bak || true) && \
|
||||
NVM_VERSION="v0.40.4" && \
|
||||
NVM_CHECKSUM="4b7412c49960c7d31e8df72da90c1fb5b8cccb419ac99537b737028d497aba4f" && \
|
||||
NODE_VERSION="v20.20.2" && \
|
||||
NVM_SCRIPT="/tmp/install-nvm.sh" && \
|
||||
curl -fsSL "https://raw.githubusercontent.com/nvm-sh/nvm/${NVM_VERSION}/install.sh" -o "$NVM_SCRIPT" && \
|
||||
echo "${NVM_CHECKSUM} ${NVM_SCRIPT}" | sha256sum -c - && \
|
||||
bash "$NVM_SCRIPT" && \
|
||||
export NVM_DIR="$HOME/.nvm" && \
|
||||
. "$NVM_DIR/nvm.sh" && \
|
||||
nvm install "${NODE_VERSION}" && \
|
||||
nvm use "${NODE_VERSION}" && \
|
||||
npm install -g npm@11.12.1 && \
|
||||
npm install -g node-gyp@12.2.0 && \
|
||||
ln -sf "$(npm root -g)/node-gyp" "$(npm root -g)/npm/node_modules/node-gyp" && \
|
||||
npm cache clean --force && \
|
||||
cd /app/ui/litellm-dashboard && \
|
||||
if [ -f "/app/enterprise/enterprise_ui/enterprise_colors.json" ]; then \
|
||||
cp /app/enterprise/enterprise_ui/enterprise_colors.json ./ui_colors.json; \
|
||||
fi && \
|
||||
([ -f .npmrc ] && mv .npmrc .npmrc.bak || true) && \
|
||||
npm ci --no-audit --no-fund && \
|
||||
([ -f .npmrc.bak ] && mv .npmrc.bak .npmrc || true) && \
|
||||
([ -f /app/.npmrc.bak ] && mv /app/.npmrc.bak /app/.npmrc || true) && \
|
||||
npm run build && \
|
||||
cp -r /app/ui/litellm-dashboard/out/* /var/lib/litellm/ui/ && \
|
||||
cp -r /app/litellm/proxy/_experimental/out/. /var/lib/litellm/ui/ && \
|
||||
cp /app/litellm/proxy/logo.jpg /var/lib/litellm/assets/logo.jpg && \
|
||||
( cd /var/lib/litellm/ui && \
|
||||
for html_file in *.html; do \
|
||||
|
|
@ -103,10 +70,10 @@ RUN mkdir -p /var/lib/litellm/ui /var/lib/litellm/assets && \
|
|||
mv "$html_file" "$folder_name/index.html"; \
|
||||
fi; \
|
||||
done && \
|
||||
touch .litellm_ui_ready ) && \
|
||||
cd /app/ui/litellm-dashboard && rm -rf ./out
|
||||
touch .litellm_ui_ready )
|
||||
|
||||
RUN if [ "$PROXY_EXTRAS_SOURCE" = "published" ]; then \
|
||||
RUN --mount=type=cache,target=/app/.cache/uv,id=litellm-uv-cache \
|
||||
if [ "$PROXY_EXTRAS_SOURCE" = "published" ]; then \
|
||||
uv sync --frozen --no-default-groups --no-editable \
|
||||
--extra proxy \
|
||||
--extra proxy-runtime \
|
||||
|
|
@ -123,10 +90,7 @@ RUN if [ "$PROXY_EXTRAS_SOURCE" = "published" ]; then \
|
|||
--python python3; \
|
||||
fi
|
||||
|
||||
RUN mkdir -p /app/.cache/npm && \
|
||||
prisma generate --schema=./schema.prisma && \
|
||||
prisma --version && \
|
||||
prisma migrate diff --from-empty --to-schema-datamodel ./schema.prisma --script > /dev/null 2>&1 || true
|
||||
RUN prisma generate --schema=./schema.prisma
|
||||
|
||||
RUN sed -i 's/\r$//' docker/entrypoint.sh && chmod +x docker/entrypoint.sh && \
|
||||
sed -i 's/\r$//' docker/prod_entrypoint.sh && chmod +x docker/prod_entrypoint.sh
|
||||
|
|
@ -137,33 +101,11 @@ WORKDIR /app
|
|||
USER root
|
||||
|
||||
RUN for i in 1 2 3; do \
|
||||
apk upgrade --no-cache && break || sleep 5; \
|
||||
apk upgrade --no-cache && break || sleep 5; \
|
||||
done && \
|
||||
for i in 1 2 3; do \
|
||||
apk add --no-cache python3 bash openssl tzdata nodejs npm supervisor libsndfile && break || sleep 5; \
|
||||
done && \
|
||||
apk upgrade --no-cache nodejs && \
|
||||
npm install -g npm@11.12.1 tar@7.5.11 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 && \
|
||||
GLOBAL="$(npm root -g)" && \
|
||||
find "$GLOBAL/npm" -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
done && \
|
||||
find "$GLOBAL/npm" -type d -name "glob" -path "*/node_modules/glob" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/glob" "$d"; \
|
||||
done && \
|
||||
find "$GLOBAL/npm" -type d -name "brace-expansion" -path "*/node_modules/@isaacs/brace-expansion" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/@isaacs/brace-expansion" "$d"; \
|
||||
done && \
|
||||
find "$GLOBAL/npm" -type d -name "minimatch" -path "*/node_modules/minimatch" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/minimatch" "$d"; \
|
||||
done && \
|
||||
find "$GLOBAL/npm" -type d -name "diff" -path "*/node_modules/diff" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/diff" "$d"; \
|
||||
done && \
|
||||
find /usr/local/lib /usr/lib -path "*/node_modules/npm/package.json" -exec \
|
||||
sed -i 's/"tar": "\^7\.5\.[0-9]*"/"tar": "^7.5.10"/g; s/"minimatch": "\^10\.[0-9.]*"/"minimatch": "^10.2.4"/g' {} + 2>/dev/null && \
|
||||
npm cache clean --force && \
|
||||
{ apk del --no-cache npm 2>/dev/null || true; }
|
||||
apk add --no-cache python3 bash openssl tzdata supervisor libsndfile nodejs && break || sleep 5; \
|
||||
done
|
||||
|
||||
COPY --from=builder /app /app
|
||||
COPY --from=builder /var/lib/litellm/ui /var/lib/litellm/ui
|
||||
|
|
@ -179,15 +121,10 @@ ENV PATH="/app/.venv/bin:${PATH}" \
|
|||
PRISMA_SKIP_POSTINSTALL_GENERATE=1 \
|
||||
PRISMA_HIDE_UPDATE_MESSAGE=1 \
|
||||
PRISMA_ENGINES_CHECKSUM_IGNORE_MISSING=1 \
|
||||
NPM_CONFIG_CACHE=/app/.cache/npm \
|
||||
NPM_CONFIG_PREFER_OFFLINE=true \
|
||||
PRISMA_OFFLINE_MODE=true
|
||||
|
||||
RUN sed -i 's/\r$//' docker/entrypoint.sh && \
|
||||
sed -i 's/\r$//' docker/prod_entrypoint.sh && \
|
||||
chmod +x docker/entrypoint.sh docker/prod_entrypoint.sh && \
|
||||
mkdir -p /nonexistent /.npm /var/lib/litellm/assets /var/lib/litellm/ui /tmp/.npm && \
|
||||
chown -R nobody:nogroup /app /var/lib/litellm/ui /var/lib/litellm/assets /nonexistent /.npm /tmp/.npm && \
|
||||
RUN mkdir -p /nonexistent /var/lib/litellm/assets /var/lib/litellm/ui && \
|
||||
chown -R nobody:nogroup /app /var/lib/litellm/ui /var/lib/litellm/assets /nonexistent && \
|
||||
PRISMA_PATH=$(python -c "import os, prisma; print(os.path.dirname(prisma.__file__))") && \
|
||||
chown -R nobody:nogroup "$PRISMA_PATH" && \
|
||||
LITELLM_PKG_MIGRATIONS_PATH="$(python -c 'import os, litellm_proxy_extras; print(os.path.dirname(litellm_proxy_extras.__file__))' 2>/dev/null || echo '')/migrations" && \
|
||||
|
|
@ -201,7 +138,7 @@ RUN sed -i 's/\r$//' docker/entrypoint.sh && \
|
|||
[ -n "$LITELLM_PROXY_EXTRAS_PATH" ] && chmod -R g+w "$LITELLM_PROXY_EXTRAS_PATH" || true && \
|
||||
chmod -R g+rX "$PRISMA_PATH" /var/lib/litellm/ui /var/lib/litellm/assets /app/.cache
|
||||
|
||||
USER nobody
|
||||
USER 65534
|
||||
|
||||
RUN prisma generate --schema=./schema.prisma
|
||||
|
||||
|
|
|
|||
|
|
@ -2,7 +2,7 @@ schemaVersion: 2.0.0
|
|||
|
||||
metadataTest:
|
||||
entrypoint: ["docker/prod_entrypoint.sh"]
|
||||
user: "nobody"
|
||||
user: "65534"
|
||||
workdir: "/app"
|
||||
|
||||
fileExistenceTests:
|
||||
|
|
|
|||
|
|
@ -479,8 +479,8 @@ For Gemini 3 Pro Preview, LiteLLM automatically maps `reasoning_effort` to the n
|
|||
| `"none"` | `"low"` | Gemini 3 cannot fully disable thinking |
|
||||
|
||||
#### Default Behavior
|
||||
LiteLLM **does not** set `thinking_level` when you omit `reasoning_effort`. The Gemini API applies its **native defaults**, matching a direct call to Google.
|
||||
|
||||
If you don't specify `reasoning_effort`, LiteLLM automatically sets `thinking_level="low"` for Gemini 3 models, to avoid high costs.
|
||||
|
||||
### Example Usage
|
||||
|
||||
|
|
@ -542,7 +542,7 @@ curl http://localhost:4000/v1/chat/completions \
|
|||
- Degraded reasoning performance
|
||||
- Failure on complex tasks
|
||||
|
||||
3. **Automatic Defaults**: If you don't specify `reasoning_effort`, LiteLLM automatically sets `thinking_level="low"` for optimal performance.
|
||||
3. **Thinking defaults come from the API**: If you omit `reasoning_effort`, LiteLLM does **not** override `thinking_level`. Set `reasoning_effort` or native thinking parameters when you want a predictable cost or latency profile (for example `reasoning_effort="low"` for lighter reasoning).
|
||||
|
||||
## Cost Tracking: Prompt Caching & Context Window
|
||||
|
||||
|
|
|
|||
172
docs/my-website/blog/gemini_embedding_2_ga/index.md
Normal file
172
docs/my-website/blog/gemini_embedding_2_ga/index.md
Normal file
|
|
@ -0,0 +1,172 @@
|
|||
---
|
||||
slug: gemini_embedding_2_ga
|
||||
title: "Gemini Embedding 2 (GA): Multimodal Embeddings on LiteLLM"
|
||||
date: 2026-04-24T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
description: "Use generally available gemini-embedding-2 for multimodal embeddings on LiteLLM via Gemini API and Vertex AI—the same flows as preview, stable model id."
|
||||
tags: [gemini, embeddings, multimodal, vertex ai]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Gemini Embedding 2 (GA): Multimodal Embeddings
|
||||
|
||||
Litellm now fully supports Gemini Embedding 2 GA.
|
||||
|
||||
:::info
|
||||
For end-to-end behavior, input shapes, and MIME types, see the [Gemini Embedding 2 Preview walkthrough](/blog/gemini_embedding_2_multimodal). This post focuses on **GA naming**, **cost map** coverage.
|
||||
:::
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
## Supported Input Types
|
||||
|
||||
| Modality | Supported Formats |
|
||||
|----------|-------------------|
|
||||
| **Text** | Plain text |
|
||||
| **Image** | PNG, JPEG |
|
||||
| **Audio** | MP3, WAV |
|
||||
| **Video** | MP4, MOV |
|
||||
| **Documents** | PDF |
|
||||
|
||||
## Input Formats
|
||||
|
||||
LiteLLM accepts three input formats for multimodal content:
|
||||
|
||||
1. **Data URIs** – Base64-encoded inline: `data:image/png;base64,<encoded_data>`
|
||||
2. **GCS URLs** – Cloud Storage paths (Vertex AI): `gs://bucket/path/to/file.png`
|
||||
3. **Gemini File References** – Pre-uploaded files (Gemini API): `files/abc123`
|
||||
|
||||
## Quick Start
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="gemini" label="Gemini API">
|
||||
|
||||
```python
|
||||
from litellm import embedding
|
||||
import os
|
||||
|
||||
os.environ["GEMINI_API_KEY"] = "your-api-key"
|
||||
|
||||
# Text + Image (base64)
|
||||
response = embedding(
|
||||
model="gemini/gemini-embedding-2",
|
||||
input=[
|
||||
"The food was delicious and the waiter...",
|
||||
"data:image/png;base64,iVBORw0KGgoAAAANSUhEUgAAAAgAAAAIAQMAAAD+wSzIAAAABlBMVEX///+/v7+jQ3Y5AAAADklEQVQI12P4AIX8EAgALgAD/aNpbtEAAAAASUVORK5CYII"
|
||||
],
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="vertex" label="Vertex AI">
|
||||
|
||||
```python
|
||||
import litellm
|
||||
from litellm import embedding
|
||||
|
||||
litellm.vertex_project = "your-project-id"
|
||||
litellm.vertex_location = "us-central1"
|
||||
|
||||
# Text + Image (GCS URL)
|
||||
response = embedding(
|
||||
model="vertex_ai/gemini-embedding-2",
|
||||
input=[
|
||||
"Describe this image",
|
||||
"gs://my-bucket/images/photo.png"
|
||||
],
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Config (config.yaml)**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gemini-embedding-2
|
||||
litellm_params:
|
||||
model: gemini/gemini-embedding-2
|
||||
api_key: os.environ/GEMINI_API_KEY
|
||||
- model_name: vertex-gemini-embedding-2
|
||||
litellm_params:
|
||||
model: vertex_ai/gemini-embedding-2
|
||||
vertex_project: os.environ/VERTEXAI_PROJECT
|
||||
vertex_location: global
|
||||
|
||||
general_settings:
|
||||
master_key: sk-1234
|
||||
```
|
||||
|
||||
**2. Start proxy**
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
**3. Call embeddings** (OpenAI-compatible **`POST /v1/embeddings`** on the proxy)
|
||||
|
||||
```bash
|
||||
curl -sS -X POST http://localhost:4000/v1/embeddings \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "gemini-embedding-2",
|
||||
"input": [
|
||||
"The food was delicious and the waiter...",
|
||||
"data:image/png;base64,iVBORw0KGgoAAAANSUhEUgAAAAgAAAAIAQMAAAD+wSzIAAAABlBMVEX///+/v7+jQ3Y5AAAADklEQVQI12P4AIX8EAgALgAD/aNpbtEAAAAASUVORK5CYII"
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Input Format Examples
|
||||
|
||||
| Format | Example | Provider |
|
||||
|--------|---------|----------|
|
||||
| **Data URI** | `data:image/png;base64,...` | Gemini, Vertex AI |
|
||||
| **GCS URL** | `gs://bucket/path/image.png` | Vertex AI |
|
||||
| **File reference** | `files/abc123` | Gemini API only |
|
||||
|
||||
### Supported MIME Types for Data URIs
|
||||
|
||||
- **Images:** `image/png`, `image/jpeg`
|
||||
- **Audio:** `audio/mpeg`, `audio/wav`
|
||||
- **Video:** `video/mp4`, `video/quicktime`
|
||||
- **Documents:** `application/pdf`
|
||||
|
||||
### GCS URL MIME Inference
|
||||
|
||||
For Vertex AI, MIME types are inferred from file extensions:
|
||||
|
||||
- `.png` → `image/png`
|
||||
- `.jpg` / `.jpeg` → `image/jpeg`
|
||||
- `.mp3` → `audio/mpeg`
|
||||
- `.wav` → `audio/wav`
|
||||
- `.mp4` → `video/mp4`
|
||||
- `.mov` → `video/quicktime`
|
||||
- `.pdf` → `application/pdf`
|
||||
|
||||
## Optional Parameters
|
||||
|
||||
| Parameter | Description | Maps to |
|
||||
|-----------|-------------|---------|
|
||||
| `dimensions` | Output embedding size | `outputDimensionality` |
|
||||
|
||||
```python
|
||||
response = embedding(
|
||||
model="gemini/gemini-embedding-2",
|
||||
input=["text to embed"],
|
||||
dimensions=768, # Optional: control output vector size
|
||||
)
|
||||
```
|
||||
155
docs/my-website/docs/adaptive_router.md
Normal file
155
docs/my-website/docs/adaptive_router.md
Normal file
|
|
@ -0,0 +1,155 @@
|
|||
# [BETA] Adaptive Router
|
||||
|
||||
:::info
|
||||
|
||||
Beta feature. Share feedback on [Discord](https://discord.gg/wuPM9dRgDw) or [Slack](https://join.slack.com/t/litellmossslack/shared_invite/zt-3o7nkuyfr-p_kbNJj8taRfXGgQI1~YyA).
|
||||
|
||||
:::
|
||||
|
||||
**Requirements:** LiteLLM Proxy with a Postgres database. Quality estimates are stored in Postgres and loaded on startup — without a database the router works but forgets everything learned on restart.
|
||||
|
||||
You have a cheap model and an expensive one. You want to use the cheap one when it's good enough, and the expensive one when it actually matters — without hardcoding rules you'll spend months tuning.
|
||||
|
||||
The adaptive router does this automatically. It tracks which model performs best for each type of request (code, writing, analysis, etc.) and routes accordingly, balancing quality against cost based on weights you control.
|
||||
|
||||
## Quick start
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-4o
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
model_info:
|
||||
input_cost_per_token: 0.0000025
|
||||
adaptive_router_preferences:
|
||||
quality_tier: 3 # 1=budget, 2=mid, 3=frontier
|
||||
strengths: ["code_generation", "analytical_reasoning"]
|
||||
|
||||
- model_name: gpt-4o-mini
|
||||
litellm_params:
|
||||
model: openai/gpt-4o-mini
|
||||
model_info:
|
||||
input_cost_per_token: 0.00000015
|
||||
adaptive_router_preferences:
|
||||
quality_tier: 2
|
||||
strengths: ["factual_lookup"]
|
||||
|
||||
- model_name: my-router
|
||||
litellm_params:
|
||||
model: auto_router/adaptive_router
|
||||
adaptive_router_config:
|
||||
available_models: ["gpt-4o", "gpt-4o-mini"]
|
||||
weights:
|
||||
quality: 0.7 # raise this if quality complaints; lower if bill too high
|
||||
cost: 0.3 # must sum to 1.0 with quality
|
||||
```
|
||||
|
||||
Route to it by setting `model` to your adaptive router's name:
|
||||
|
||||
```bash
|
||||
curl -X POST {{baseURL}}/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer $LITELLM_API_KEY" \
|
||||
-d '{
|
||||
"model": "my-router",
|
||||
"messages": [
|
||||
{"role": "user", "content": "build me a python script that parses CSV"},
|
||||
{"role": "assistant", "content": "Here is a script using csv.DictReader..."},
|
||||
{"role": "user", "content": "now add error handling for missing files"},
|
||||
{"role": "assistant", "content": "Wrap the open() call in a try/except FileNotFoundError..."},
|
||||
{"role": "user", "content": "perfect, that worked. thanks!"}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
The response includes a header telling you which model was actually picked:
|
||||
|
||||
```
|
||||
x-litellm-adaptive-router-model: gpt-4o
|
||||
```
|
||||
|
||||
The "thanks!" turn in the example above fires a satisfaction signal — that's what moves the bandit.
|
||||
|
||||
## Tuning cost vs. quality
|
||||
|
||||
The `weights` are your main lever:
|
||||
|
||||
| Goal | quality | cost |
|
||||
|---|---|---|
|
||||
| Minimize cost, quality is secondary | 0.3 | 0.7 |
|
||||
| Balanced | 0.5 | 0.5 |
|
||||
| Quality-first (default) | 0.7 | 0.3 |
|
||||
| Quality non-negotiable | 0.9 | 0.1 |
|
||||
|
||||
The router learns over time. For the first ~10 requests per model, it relies on the tiers you declared. After that, real performance data takes over.
|
||||
|
||||
## Force a minimum quality tier per request
|
||||
|
||||
If a specific request needs a frontier model regardless of cost, pass this header:
|
||||
|
||||
```
|
||||
x-litellm-min-quality-tier: 3
|
||||
```
|
||||
|
||||
You can also pass `min_quality_tier` via request metadata instead of a header.
|
||||
|
||||
## What's being learned
|
||||
|
||||
The router classifies each request into one of 7 types and tracks how each model performs on each independently. A model that's great at factual lookup but poor at code will win factual requests and lose code requests — even if it's cheaper overall.
|
||||
|
||||
| Type | Example |
|
||||
|---|---|
|
||||
| `code_generation` | "write me a Python sort function" |
|
||||
| `code_understanding` | "explain what this function does" |
|
||||
| `technical_design` | "how should I design this API?" |
|
||||
| `analytical_reasoning` | "calculate the probability that..." |
|
||||
| `writing` | "draft an email to my team about..." |
|
||||
| `factual_lookup` | "what is the capital of France?" |
|
||||
| `general` | anything else |
|
||||
|
||||
[**See classifier code**](https://github.com/BerriAI/litellm/blob/litellm_adaptive_routing/litellm/router_strategy/adaptive_router/classifier.py)
|
||||
|
||||
Learning signals are inspired by [Signals: Trajectory Sampling and Triage for Agentic Interactions](https://arxiv.org/pdf/2604.00356).
|
||||
|
||||
## Inspect the current state
|
||||
|
||||
```
|
||||
GET /adaptive_router/{router_name}/state
|
||||
```
|
||||
|
||||
Returns current quality estimates per model per request type. Useful for understanding why a model is or isn't being picked.
|
||||
|
||||
```json
|
||||
{
|
||||
"routers": [
|
||||
{
|
||||
"router_name": "smart-cheap-router",
|
||||
"available_models": ["fast", "smart"],
|
||||
"weights": { "quality": 0.7, "cost": 0.3 },
|
||||
"cells": [
|
||||
{
|
||||
"request_type": "analytical_reasoning",
|
||||
"model": "fast",
|
||||
"quality_mean": 0.5,
|
||||
"samples": 0
|
||||
},
|
||||
{
|
||||
"request_type": "analytical_reasoning",
|
||||
"model": "smart",
|
||||
"quality_mean": 0.95,
|
||||
"samples": 0
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
`quality_mean` is the key number — it's the router's current estimate of how well that model handles that request type. `samples` counts how many real observations have moved the prior (starts at 0; the cold-start prior mass is excluded).
|
||||
|
||||
## Known limitations
|
||||
|
||||
- Latency isn't scored — a slow model can still win on quality + cost
|
||||
- Signals are regex-based and English-biased — no LLM judge
|
||||
- Hard cap of 200 observations per cell; no decay yet
|
||||
- Once a model is picked for a session, other models' turns in that session don't contribute to learning
|
||||
|
|
@ -10,6 +10,7 @@ Supported Providers:
|
|||
- Vertex AI (`vertex_ai/`, `vertex_ai_beta/`)
|
||||
- Bedrock (`bedrock/`, `bedrock/invoke/`, `bedrock/converse`) ([All models bedrock supports prompt caching on](https://docs.aws.amazon.com/bedrock/latest/userguide/prompt-caching.html))
|
||||
- Deepseek API (`deepseek/`)
|
||||
- xAI (`xai/`)
|
||||
|
||||
For the supported providers, LiteLLM follows the OpenAI prompt caching usage object format:
|
||||
|
||||
|
|
|
|||
|
|
@ -8,6 +8,7 @@ The function keeps high-relevance and recent context, replaces low-relevance con
|
|||
|
||||
```python
|
||||
import litellm
|
||||
from litellm.types.utils import CallTypes
|
||||
|
||||
messages = [
|
||||
{"role": "system", "content": "You are a coding assistant."},
|
||||
|
|
@ -19,6 +20,7 @@ messages = [
|
|||
compressed = litellm.compress(
|
||||
messages=messages,
|
||||
model="gpt-4o",
|
||||
call_type=CallTypes.completion,
|
||||
compression_trigger=1000,
|
||||
compression_target=500,
|
||||
)
|
||||
|
|
@ -45,6 +47,7 @@ response = litellm.completion(
|
|||
|
||||
- `messages` (`List[dict]`, required): input conversation messages
|
||||
- `model` (`str`, required): model name used for token counting
|
||||
- `call_type` (`CallTypes`, default `CallTypes.completion`): the LiteLLM call type whose message schema these messages follow. Supported values: `CallTypes.completion` / `CallTypes.acompletion` (OpenAI chat-completions shape) and `CallTypes.anthropic_messages` (Anthropic Messages shape)
|
||||
- `compression_trigger` (`int`, default `200000`): compress only if input token count exceeds this
|
||||
- `compression_target` (`Optional[int]`, default `70% of compression_trigger`): desired post-compression token budget
|
||||
- `embedding_model` (`Optional[str]`): if set, combines BM25 + embedding relevance scoring
|
||||
|
|
@ -70,6 +73,28 @@ args = json.loads(tool_call.function.arguments)
|
|||
full_content = compressed["cache"][args["key"]]
|
||||
```
|
||||
|
||||
## Server-side Callback Loop (`/v1/messages`)
|
||||
|
||||
You can enable callback-based compression interception to make retrieval loops
|
||||
transparent for Anthropic Messages calls:
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
callbacks: ["compression_interception"]
|
||||
compression_interception_params:
|
||||
enabled: true
|
||||
compression_trigger: 10000
|
||||
compression_target: 7000
|
||||
```
|
||||
|
||||
With this enabled, LiteLLM runs the following server-side flow:
|
||||
|
||||
1. Compresses inbound messages before the first provider call.
|
||||
2. Injects the `litellm_content_retrieve` tool.
|
||||
3. Detects retrieval `tool_use` blocks in the model response.
|
||||
4. Resolves retrieval keys from the compression cache.
|
||||
5. Reruns the model via agentic loop and returns the final answer.
|
||||
|
||||
## Performance
|
||||
|
||||
Benchmarked on [SWE-bench Lite](https://huggingface.co/datasets/princeton-nlp/SWE-bench_Lite_bm25_27K) (real GitHub issues with ~27k tokens of BM25-retrieved repo context per problem).
|
||||
|
|
|
|||
|
|
@ -596,3 +596,87 @@ Expected Response
|
|||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Web Search Cost Tracking
|
||||
|
||||
LiteLLM tracks web search costs automatically based on provider-specific billing models. The cost is added on top of the standard token-based pricing.
|
||||
|
||||
### How providers charge for web search
|
||||
|
||||
| Provider | Billing Unit | How it works |
|
||||
|----------|-------------|--------------|
|
||||
| **Gemini 3.x** (3-flash, 3-pro, 3.1-*) | Per search query | Each internal search query is billed individually. One prompt may trigger multiple queries. |
|
||||
| **Gemini 2.x** (2.0-flash, 2.5-flash, 2.5-pro) | Per grounded prompt | Flat fee per API call that uses grounding, regardless of how many queries are executed internally. |
|
||||
| **OpenAI** (gpt-4o-search, gpt-5-search) | Per search context size | Cost varies by `search_context_size` (`low`, `medium`, `high`). |
|
||||
| **Anthropic** (Claude with web search) | Per search request | Fixed cost per web search tool invocation. |
|
||||
| **Perplexity** (sonar, sonar-pro) | Per search context size | Cost varies by `search_context_size`. |
|
||||
|
||||
### Pricing configuration
|
||||
|
||||
Web search costs are defined in `model_prices_and_context_window.json` using two fields:
|
||||
|
||||
- **`search_context_cost_per_query`**: the cost per billable unit (per search context size tier).
|
||||
- **`web_search_billing_unit`** *(on Gemini models)*: `"per_query"` (each search query is billed individually) or `"per_prompt"` (default — flat fee per API call that uses search).
|
||||
|
||||
```json
|
||||
{
|
||||
"gemini/gemini-3-flash-preview": {
|
||||
"web_search_billing_unit": "per_query",
|
||||
"search_context_cost_per_query": {
|
||||
"search_context_size_low": 0.014,
|
||||
"search_context_size_medium": 0.014,
|
||||
"search_context_size_high": 0.014
|
||||
}
|
||||
},
|
||||
"gemini/gemini-2.5-flash": {
|
||||
"search_context_cost_per_query": {
|
||||
"search_context_size_low": 0.035,
|
||||
"search_context_size_medium": 0.035,
|
||||
"search_context_size_high": 0.035
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
:::info
|
||||
Models without `web_search_billing_unit` default to `"per_prompt"` — one flat charge per API call that uses web search, regardless of how many internal queries the model executes.
|
||||
:::
|
||||
|
||||
You can override these in your proxy config using `model_info`:
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gemini-3-flash
|
||||
litellm_params:
|
||||
model: gemini/gemini-3-flash-preview
|
||||
model_info:
|
||||
web_search_billing_unit: per_query
|
||||
search_context_cost_per_query:
|
||||
search_context_size_low: 0.014
|
||||
search_context_size_medium: 0.014
|
||||
search_context_size_high: 0.014
|
||||
```
|
||||
|
||||
### How LiteLLM tracks search usage
|
||||
|
||||
The number of web search requests is stored in `usage.prompt_tokens_details.web_search_requests`. LiteLLM extracts this from each provider's response:
|
||||
|
||||
- **Gemini**: Extracted from `groundingMetadata.webSearchQueries` in the response. For Gemini 2.x, clamped to 1 (per-prompt billing).
|
||||
- **OpenAI**: Reported directly in the usage metadata.
|
||||
- **Anthropic**: Reported via `server_tool_use.web_search_requests`.
|
||||
- **xAI**: Mapped from `num_sources_used` in the response.
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="gemini/gemini-3-flash-preview",
|
||||
messages=[{"role": "user", "content": "Latest tech news?"}],
|
||||
web_search_options={"search_context_size": "medium"},
|
||||
)
|
||||
|
||||
# Check web search usage
|
||||
print(response.usage.prompt_tokens_details.web_search_requests) # e.g., 3
|
||||
|
||||
# Get total cost (includes token cost + web search cost)
|
||||
cost = litellm.completion_cost(completion_response=response)
|
||||
print(f"Total cost: ${cost}")
|
||||
```
|
||||
|
|
|
|||
|
|
@ -83,7 +83,7 @@ Note: Reasoning cannot be turned off on Gemini 2.5 Pro models.
|
|||
:::
|
||||
|
||||
:::tip Gemini 3 Models
|
||||
For **Gemini 3+ models** (e.g., `gemini-3-pro-preview`), LiteLLM automatically maps `reasoning_effort` to the new `thinking_level` parameter instead of `thinking_budget`. The `thinking_level` parameter uses `"low"` or `"high"` values for better control over reasoning depth.
|
||||
For **Gemini 3+ models** (e.g., `gemini-3-pro-preview`), LiteLLM maps `reasoning_effort` to the `thinking_level` field instead of `thinking_budget` when you set it. Supported levels depend on the model (Flash-family models also support `minimal` and `medium`). If you omit `reasoning_effort`, LiteLLM does **not** send a default `thinking_level` — the request uses the **Gemini API defaults** (Gemini 3 Flash defaults to `high` on the API).
|
||||
:::
|
||||
|
||||
:::warning Image Models
|
||||
|
|
@ -104,12 +104,12 @@ For **Gemini 3+ models** (e.g., `gemini-3-pro-preview`), LiteLLM automatically m
|
|||
|
||||
| reasoning_effort | thinking_level | Notes |
|
||||
| ---------------- | -------------- | ----- |
|
||||
| "minimal" | "low" | Minimizes latency and cost |
|
||||
| "minimal" | `"minimal"` (Flash / some 3.1) or `"low"` | Flash-family IDs use `minimal` when supported |
|
||||
| "low" | "low" | Best for simple instruction following or chat |
|
||||
| "medium" | "high" | Maps to high (medium not yet available) |
|
||||
| "medium" | `"medium"` or `"high"` | `"medium"` where the API supports it; otherwise `"high"` |
|
||||
| "high" | "high" | Maximizes reasoning depth |
|
||||
| "disable" | "low" | Cannot fully disable thinking in Gemini 3 |
|
||||
| "none" | "low" | Cannot fully disable thinking in Gemini 3 |
|
||||
| "disable" | `"minimal"` (Flash) or `"low"` | Cannot fully disable thinking in Gemini 3 |
|
||||
| "none" | `"minimal"` (Flash) or `"low"` | Cannot fully disable thinking in Gemini 3 |
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
|
|
|||
|
|
@ -192,6 +192,13 @@ export GITHUB_COPILOT_ACCESS_TOKEN_FILE="access-token"
|
|||
|
||||
# Optional: Custom API key file name
|
||||
export GITHUB_COPILOT_API_KEY_FILE="api-key.json"
|
||||
|
||||
# Optional: Custom Copilot endpoints for authentication and usage
|
||||
# (needed when using GitHub Enterprise subscriptions with custom endpoints or self-hosted GitHub servers
|
||||
export GITHUB_COPILOT_API_BASE="https://copilot-api.my-company.ghe.com"
|
||||
export GITHUB_COPILOT_DEVICE_CODE_URL="https://my-company.ghe.com/login/device/code"
|
||||
export GITHUB_COPILOT_ACCESS_TOKEN_URL="https://my-company.ghe.com/login/oauth/access_token"
|
||||
export GITHUB_COPILOT_API_KEY_URL="https://my-company.ghe.com/api/v3/copilot_internal/v2/token"
|
||||
```
|
||||
|
||||
### Headers
|
||||
|
|
|
|||
|
|
@ -432,9 +432,59 @@ curl -X POST 'http://0.0.0.0:4000/chat/completions' \
|
|||
| fine tuned `gpt-3.5-turbo-1106` | `response = completion(model="ft:gpt-3.5-turbo-1106", messages=messages)` |
|
||||
| fine tuned `gpt-3.5-turbo-0613` | `response = completion(model="ft:gpt-3.5-turbo-0613", messages=messages)` |
|
||||
|
||||
## Getting Reasoning Content in `/chat/completions`
|
||||
## [BETA] Route all .completions requests to Responses API (better quality)
|
||||
When enabled, LiteLLM sends OpenAI traffic from `litellm.completion()` and the proxy `/chat/completions` endpoint through the [Responses API](https://platform.openai.com/docs/api-reference/responses) instead of Chat Completions. That path generally matches OpenAI’s latest model behavior and quality (for example, reasoning output on GPT‑5 class models).
|
||||
|
||||
GPT-5 models return reasoning content when called via the Responses API. You can call these models via the `/chat/completions` endpoint by using the `openai/responses/` prefix.
|
||||
You can opt in globally or per request:
|
||||
|
||||
**Option A — per-request prefix:** Use the `openai/responses/` model prefix.
|
||||
|
||||
**Option B — global flag (recommended):** Set `route_all_chat_openai_to_responses = True` to automatically route all OpenAI `/chat/completions` requests through the Responses API, no model prefix needed.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk-global" label="SDK - Global Flag">
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
litellm.route_all_chat_openai_to_responses = True
|
||||
|
||||
response = litellm.completion(
|
||||
model="gpt-5.4",
|
||||
messages=[{"role": "user", "content": "What is the capital of France?"}],
|
||||
reasoning_effort="low",
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy-global" label="PROXY - Global Flag">
|
||||
|
||||
Set in your proxy config:
|
||||
```yaml
|
||||
litellm_settings:
|
||||
route_all_chat_openai_to_responses: true
|
||||
```
|
||||
|
||||
Then call normally — no model prefix needed:
|
||||
```bash
|
||||
curl -X POST 'http://0.0.0.0:4000/chat/completions' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-d '{
|
||||
"model": "gpt-5.4",
|
||||
"messages": [{"role": "user", "content": "What is the capital of France?"}],
|
||||
"reasoning_effort": "low"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
:::note
|
||||
`route_all_chat_openai_to_responses` only applies to the `openai` provider. Azure OpenAI is unaffected. You can also set it via env var: `LITELLM_ROUTE_ALL_CHAT_OPENAI_TO_RESPONSES=true`.
|
||||
:::
|
||||
|
||||
**Option A — per-request prefix:** You can also prefix individual model names with `openai/responses/` to route just that call through the Responses API.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
|
|
|||
|
|
@ -60,3 +60,44 @@ curl http://localhost:4000/chat/completions \
|
|||
## Supported features
|
||||
|
||||
Scaleway provider supports all features in [Generative APIs reference documentation ↗](https://www.scaleway.com/en/developers/api/generative-apis/), such as streaming, structured outputs and tool calling.
|
||||
|
||||
## Audio transcription
|
||||
|
||||
Scaleway's `/audio/transcriptions` endpoint is OpenAI-compatible and works with Whisper models.
|
||||
|
||||
### Python SDK
|
||||
|
||||
```python
|
||||
import os
|
||||
from litellm import transcription
|
||||
|
||||
os.environ["SCW_SECRET_KEY"] = "your-scaleway-secret-key"
|
||||
|
||||
with open("speech.mp3", "rb") as audio_file:
|
||||
response = transcription(
|
||||
model="scaleway/whisper-large-v3",
|
||||
file=audio_file,
|
||||
)
|
||||
print(response.text)
|
||||
```
|
||||
|
||||
### Proxy config
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: scaleway-whisper
|
||||
litellm_params:
|
||||
model: scaleway/whisper-large-v3
|
||||
api_key: "os.environ/SCW_SECRET_KEY"
|
||||
```
|
||||
|
||||
### Proxy request
|
||||
|
||||
```bash
|
||||
curl http://localhost:4000/v1/audio/transcriptions \
|
||||
-H "Authorization: Bearer YOUR_LITELLM_MASTER_KEY" \
|
||||
-F model="scaleway-whisper" \
|
||||
-F file="@speech.mp3"
|
||||
```
|
||||
|
||||
Supported optional params: `language`, `prompt`, `response_format`, `temperature`, `timestamp_granularities`.
|
||||
|
|
|
|||
|
|
@ -2061,7 +2061,7 @@ assert isinstance(
|
|||
|
||||
## Media Resolution Control (Images & Videos)
|
||||
|
||||
For Gemini 3+ models, LiteLLM supports per-part media resolution control using OpenAI's `detail` parameter. This allows you to specify different resolution levels for individual images and videos in your request, whether using `image_url` or `file` content types.
|
||||
LiteLLM supports per-part media resolution control using OpenAI's `detail` parameter for all Gemini models. This allows you to specify different resolution levels for individual images and videos in your request, whether using `image_url` or `file` content types.
|
||||
|
||||
**Supported `detail` values:**
|
||||
- `"low"` - Maps to `media_resolution: "low"` (280 tokens for images, 70 tokens per frame for videos)
|
||||
|
|
@ -2146,12 +2146,12 @@ response = completion(
|
|||
</Tabs>
|
||||
|
||||
:::info
|
||||
**Per-Part Resolution:** Each image or video in your request can have its own `detail` setting, allowing mixed-resolution requests (e.g., a high-res chart alongside a low-res icon). This feature works with both `image_url` and `file` content types, and is only available for Gemini 3+ models.
|
||||
**Per-Part Resolution:** Each image or video in your request can have its own `detail` setting, allowing mixed-resolution requests (e.g., a high-res chart alongside a low-res icon). This feature works with both `image_url` and `file` content types across all Gemini models.
|
||||
:::
|
||||
|
||||
## Video Metadata Control
|
||||
|
||||
For Gemini 3+ models, LiteLLM supports fine-grained video processing control through the `video_metadata` field. This allows you to specify frame extraction rates and time ranges for video analysis.
|
||||
LiteLLM supports fine-grained video processing control through the `video_metadata` field for all Gemini models (1.x, 2.x, 3+). This allows you to specify frame extraction rates and time ranges for video analysis.
|
||||
|
||||
**Supported `video_metadata` parameters:**
|
||||
|
||||
|
|
@ -2168,8 +2168,11 @@ For Gemini 3+ models, LiteLLM supports fine-grained video processing control thr
|
|||
- `fps` remains unchanged
|
||||
:::
|
||||
|
||||
:::tip
|
||||
Video clipping (`start_offset`/`end_offset`) and frame rate control (`fps`) are supported by all Gemini models, but analysis quality is significantly higher with the **Gemini 2.5 series** (e.g., `gemini-2.5-flash`, `gemini-2.5-pro`).
|
||||
:::
|
||||
|
||||
:::warning
|
||||
- **Gemini 3+ Only:** This feature is only available for Gemini 3.0 and newer models
|
||||
- **Video Files Recommended:** While `video_metadata` is designed for video files, error handling for other media types is delegated to the Vertex AI API
|
||||
- **File Formats Supported:** Works with `gs://`, `https://`, and base64-encoded video files
|
||||
:::
|
||||
|
|
|
|||
95
docs/my-website/docs/proxy/agentic_loop_hook.md
Normal file
95
docs/my-website/docs/proxy/agentic_loop_hook.md
Normal file
|
|
@ -0,0 +1,95 @@
|
|||
# Agentic Loop Hook
|
||||
|
||||
Build a `CustomLogger` callback that intercepts a model response, fulfills tool calls server-side, and reruns the model — transparently to the caller.
|
||||
|
||||
:::info Supported call types
|
||||
- `async` only (sync calls do not trigger the hook)
|
||||
- Non-streaming only (streaming responses cannot be inspected for tool calls)
|
||||
- Works on both `/v1/messages` and `/v1/chat/completions`
|
||||
:::
|
||||
|
||||
## Implement the callback
|
||||
|
||||
Override two methods on `CustomLogger`:
|
||||
|
||||
```python
|
||||
from litellm.integrations.custom_logger import CustomLogger
|
||||
from litellm.types.integrations.custom_logger import AgenticLoopPlan, AgenticLoopRequestPatch
|
||||
|
||||
MY_TOOL = "my_tool"
|
||||
|
||||
class MyToolCallback(CustomLogger):
|
||||
|
||||
async def async_should_run_agentic_loop(
|
||||
self, response, model, messages, tools, stream, custom_llm_provider, kwargs
|
||||
):
|
||||
# Return (True, context_dict) if there are tool calls to handle
|
||||
content = getattr(response, "content", None) or []
|
||||
calls = [b for b in content if isinstance(b, dict)
|
||||
and b.get("type") == "tool_use" and b.get("name") == MY_TOOL]
|
||||
if not calls:
|
||||
return False, {}
|
||||
return True, {"tool_calls": calls}
|
||||
|
||||
async def async_build_agentic_loop_plan(
|
||||
self, tools, model, messages, response,
|
||||
anthropic_messages_provider_config,
|
||||
anthropic_messages_optional_request_params,
|
||||
logging_obj, stream, kwargs,
|
||||
):
|
||||
calls = tools["tool_calls"]
|
||||
results = [f"result for {c['input']}" for c in calls] # your logic here
|
||||
|
||||
follow_up = messages + [
|
||||
{"role": "assistant", "content": [
|
||||
{"type": "tool_use", "id": c["id"], "name": c["name"], "input": c["input"]}
|
||||
for c in calls
|
||||
]},
|
||||
{"role": "user", "content": [
|
||||
{"type": "tool_result", "tool_use_id": c["id"], "content": results[i]}
|
||||
for i, c in enumerate(calls)
|
||||
]},
|
||||
]
|
||||
return AgenticLoopPlan(
|
||||
run_agentic_loop=True,
|
||||
request_patch=AgenticLoopRequestPatch(messages=follow_up),
|
||||
)
|
||||
```
|
||||
|
||||
For `/v1/chat/completions`, override `async_build_chat_completion_agentic_loop_plan` instead — same idea, `optional_params` replaces `anthropic_messages_optional_request_params`.
|
||||
|
||||
## Register it
|
||||
|
||||
```python
|
||||
import litellm
|
||||
litellm.callbacks = [MyToolCallback()]
|
||||
```
|
||||
|
||||
Or in `config.yaml`:
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
callbacks: ["my_module.MyToolCallback"]
|
||||
```
|
||||
|
||||
## `AgenticLoopPlan` fields
|
||||
|
||||
| Field | Effect |
|
||||
|---|---|
|
||||
| `run_agentic_loop=True` + `request_patch` | Reruns the model with the patched request |
|
||||
| `response_override` | Returns this value directly to the caller (no rerun) |
|
||||
| `terminate=True` | Stops the loop, returns the current response |
|
||||
| `run_agentic_loop=False` (default) | Skips; next callback is checked |
|
||||
|
||||
`AgenticLoopRequestPatch` accepts: `model`, `messages`, `tools`, `max_tokens`, `optional_params`, `kwargs`.
|
||||
|
||||
## Loop safety
|
||||
|
||||
- Default max reruns: `3` — override per-request with `kwargs["max_agentic_loops"]`
|
||||
- Identical tool-call fingerprints abort the loop automatically
|
||||
- Current depth is in `kwargs["_agentic_loop_depth"]`
|
||||
|
||||
## Examples in this repo
|
||||
|
||||
- `litellm/integrations/compression_interception/handler.py`
|
||||
- `litellm/integrations/websearch_interception/handler.py`
|
||||
|
|
@ -197,6 +197,7 @@ router_settings:
|
|||
| key_generation_settings | object | Restricts who can generate keys. [Further docs](./virtual_keys.md#restricting-key-generation) |
|
||||
| disable_add_transform_inline_image_block | boolean | For Fireworks AI models - if true, turns off the auto-add of `#transform=inline` to the url of the image_url, if the model is not a vision model. |
|
||||
| use_chat_completions_url_for_anthropic_messages | boolean | If true, routes OpenAI `/v1/messages` requests through chat/completions instead of the Responses API. Can also be set via env var `LITELLM_USE_CHAT_COMPLETIONS_URL_FOR_ANTHROPIC_MESSAGES=true`. |
|
||||
| route_all_chat_openai_to_responses | boolean | If true, routes all OpenAI `/chat/completions` requests through the Responses API bridge. Recommended for OpenAI models. Can also be set via env var `LITELLM_ROUTE_ALL_CHAT_OPENAI_TO_RESPONSES=true`. |
|
||||
| skip_system_message_in_guardrail | boolean | If true, unified guardrails omit `role: system` from scanned input on **chat completions** and **Anthropic `/v1/messages`** only; the LLM still receives full messages. Per-guardrail override: `litellm_params.skip_system_message_in_guardrail` on each guardrail. [Guardrails quick start](./guardrails/quick_start#skip-system-messages-in-guardrail-evaluation) |
|
||||
| disable_hf_tokenizer_download | boolean | If true, it defaults to using the openai tokenizer for all models (including huggingface models). |
|
||||
| enable_json_schema_validation | boolean | If true, enables json schema validation for all requests. |
|
||||
|
|
@ -487,7 +488,8 @@ router_settings:
|
|||
| AZURE_STORAGE_CLIENT_ID | The Application Client ID to use for Authentication to Azure Blob Storage logging
|
||||
| AZURE_STORAGE_CLIENT_SECRET | The Application Client Secret to use for Authentication to Azure Blob Storage logging
|
||||
| AZURE_VECTOR_STORE_COST_PER_GB_PER_DAY | Cost per GB per day for Azure Vector Store service
|
||||
| BACKGROUND_HEALTH_CHECK_MAX_TOKENS | Optional global default for `max_tokens` on proxy background health checks when a model has no `health_check_max_tokens`. If unset, non-wildcard models default to 1. Applies to wildcard routes when set. Default is unset
|
||||
| BACKGROUND_HEALTH_CHECK_MAX_TOKENS | Optional global default for `max_tokens` on proxy background health checks when a model has no `health_check_max_tokens`. If unset, non-wildcard models default to 5. Applies to wildcard routes when set. Default is unset
|
||||
| BACKGROUND_HEALTH_CHECK_MAX_TOKENS_REASONING | For **non-wildcard** reasoning models (`supports_reasoning(model)=true`), this takes precedence over `BACKGROUND_HEALTH_CHECK_MAX_TOKENS` when set. If unset, reasoning models fall back to `BACKGROUND_HEALTH_CHECK_MAX_TOKENS` (if set) or default behavior. Wildcard routes ignore this. Default is unset
|
||||
| BATCH_STATUS_POLL_INTERVAL_SECONDS | Interval in seconds for polling batch status. Default is 3600 (1 hour)
|
||||
| BATCH_STATUS_POLL_MAX_ATTEMPTS | Maximum number of attempts for polling batch status. Default is 24 (for 24 hours)
|
||||
| BEDROCK_MAX_POLICY_SIZE | Maximum size for Bedrock policy. Default is 75
|
||||
|
|
@ -720,6 +722,11 @@ router_settings:
|
|||
| GITHUB_COPILOT_TOKEN_DIR | Directory to store GitHub Copilot token for `github_copilot` llm provider
|
||||
| GITHUB_COPILOT_API_KEY_FILE | File to store GitHub Copilot API key for `github_copilot` llm provider
|
||||
| GITHUB_COPILOT_ACCESS_TOKEN_FILE | File to store GitHub Copilot access token for `github_copilot` llm provider
|
||||
| GITHUB_COPILOT_API_BASE | Base URL for GitHub Copilot API. For GitHub Enterprise subscriptions with custom host, it is similar to https://copilot-api.my-company.ghe.com. Default is https://api.githubcopilot.com
|
||||
| GITHUB_COPILOT_DEVICE_CODE_URL | URL for GitHub Copilot device code authentication. For GitHub Enterprise subscriptions with custom host, it is similar to https://my-company.ghe.com/login/device/code. Default is https://github.com/login/device/code
|
||||
| GITHUB_COPILOT_ACCESS_TOKEN_URL | URL for GitHub Copilot access token retrieval. For GitHub Enterprise subscriptions with custom host, it is similar to https://my-company.ghe.com/login/oauth/access_token. Default is https://github.com/login/oauth/access_token
|
||||
| GITHUB_COPILOT_API_KEY_URL | URL for GitHub Copilot API key retrieval. For GitHub Enterprise subscriptions with custom host, it is similar to https://my-company.ghe.com/api/v3/copilot_internal/v2/token. Default is https://api.github.com/copilot_internal/v2/token
|
||||
| GITHUB_COPILOT_CLIENT_ID | Client ID for GitHub Copilot device flow authentication. This is used by the `github_copilot` provider for device code authentication. Default is "Iv1.b507a08c87ecfe98"
|
||||
| GREENSCALE_API_KEY | API key for Greenscale service
|
||||
| GREENSCALE_ENDPOINT | Endpoint URL for Greenscale service
|
||||
| GRAYSWAN_API_BASE | Base URL for GraySwan API. Default is https://api.grayswan.ai
|
||||
|
|
@ -862,6 +869,7 @@ router_settings:
|
|||
| LITELLM_SECRET_AWS_KMS_LITELLM_LICENSE | AWS KMS encrypted license for LiteLLM
|
||||
| LITELLM_TOKEN | Access token for LiteLLM integration
|
||||
| LITELLM_USE_CHAT_COMPLETIONS_URL_FOR_ANTHROPIC_MESSAGES | When set to "true", routes OpenAI /v1/messages requests through chat/completions instead of the Responses API for Anthropic models. Can also be set via `litellm_settings.use_chat_completions_url_for_anthropic_messages`
|
||||
| LITELLM_ROUTE_ALL_CHAT_OPENAI_TO_RESPONSES | When set to "true", routes all OpenAI /chat/completions requests through the Responses API bridge. Recommended for OpenAI models. Can also be set via `litellm_settings.route_all_chat_openai_to_responses`
|
||||
| LITELLM_USER_AGENT | Custom user agent string for LiteLLM API requests. Used for partner telemetry attribution
|
||||
| LITELLM_WORKER_STARTUP_HOOKS | Comma-separated list of `module.path:function_name` callables to run in each worker process during startup. Runs early in the worker lifecycle (before config/DB loading). Useful for re-initializing per-process state like [gflags](https://github.com/google/python-gflags). See [Worker Startup Hooks](/proxy/worker_startup_hooks) for details
|
||||
| LITELLM_PRINT_STANDARD_LOGGING_PAYLOAD | If true, prints the standard logging payload to the console - useful for debugging
|
||||
|
|
|
|||
|
|
@ -338,7 +338,7 @@ model_list:
|
|||
|
||||
## Health Check Max Tokens
|
||||
|
||||
By default, health checks use `max_tokens=1` to minimize cost and latency. For wildcard models, the default is `max_tokens=10`.
|
||||
By default, health checks use `max_tokens=5` to balance reliability with low cost and latency. For wildcard models, the default is `max_tokens=10`.
|
||||
|
||||
You can override this per-model by setting `health_check_max_tokens` in the `model_info` section of your config.yaml.
|
||||
|
||||
|
|
@ -352,6 +352,30 @@ model_list:
|
|||
health_check_max_tokens: 5 # 👈 OVERRIDE HEALTH CHECK MAX TOKENS
|
||||
```
|
||||
|
||||
### Reasoning vs non-reasoning defaults
|
||||
|
||||
Reasoning models (per `supports_reasoning` in the model map) often need a higher health-check `max_tokens` because providers count reasoning tokens toward the completion budget. You can set **separate** limits without listing every model:
|
||||
|
||||
**Per deployment (`model_info`)** — used when `health_check_max_tokens` is not set. Ignored for wildcard routes (`*` in `litellm_params.model`, i.e. the deployment model string; not `health_check_model`).
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: openai-stack
|
||||
litellm_params:
|
||||
model: openai/gpt-5-nano
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
model_info:
|
||||
health_check_max_tokens_reasoning: 128
|
||||
health_check_max_tokens_non_reasoning: 1
|
||||
```
|
||||
|
||||
**Global (environment)**:
|
||||
|
||||
- `BACKGROUND_HEALTH_CHECK_MAX_TOKENS_REASONING` — for non-wildcard reasoning models, this value takes precedence when set
|
||||
- `BACKGROUND_HEALTH_CHECK_MAX_TOKENS` — global fallback for all models (including wildcard routes)
|
||||
|
||||
If neither is set, non-wildcard models default to `5` and wildcard routes omit `max_tokens`.
|
||||
|
||||
## `/health/readiness`
|
||||
|
||||
Unprotected endpoint for checking if proxy is ready to accept requests
|
||||
|
|
|
|||
|
|
@ -51,11 +51,42 @@ These headers are useful for clients to understand the current rate limit status
|
|||
## LiteLLM Specific Headers
|
||||
| Header | Type | Description | Available on Pass-Through Endpoints |
|
||||
|--------|------|-------------|-------------|
|
||||
| `x-litellm-call-id` | string | Unique identifier for the API call | ✅ |
|
||||
| `x-litellm-model-id` | string | Unique identifier for the model used | |
|
||||
| `x-litellm-model-api-base` | string | Base URL of the API endpoint | ✅ |
|
||||
| `x-litellm-version` | string | Version of LiteLLM being used | |
|
||||
| `x-litellm-model-group` | string | Model group identifier | |
|
||||
| `x-litellm-call-id` | string | Id for this request | ✅ |
|
||||
| `x-litellm-model-id` | string | Deployment id (`model_info.id`) | |
|
||||
| `x-litellm-model-api-base` | string | API base URL | ✅ |
|
||||
| `x-litellm-version` | string | LiteLLM version | |
|
||||
| `x-litellm-model-group` | string | Routed `model_list[].model_name` (client `model`) | |
|
||||
|
||||
### Example
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: my-chat-model # clients call this
|
||||
litellm_params:
|
||||
model: gpt-4o-mini # LiteLLM calls this upstream
|
||||
model_info:
|
||||
id: "7c9f2a1b3d8e4f0a2c6b5d9e1f3a7b8c" # optional; auto-generated if omitted
|
||||
```
|
||||
|
||||
| Header | Example | Notes |
|
||||
|--------|---------|-------|
|
||||
| `x-litellm-model-group` | `my-chat-model` | `model_name` / request `model`; not `litellm_params.model`. |
|
||||
| `x-litellm-model-id` | `7c9f2a1b3d8e4f0a2c6b5d9e1f3a7b8c` | Which deployment row; use with `/v1/model/info?litellm_model_id=...`. |
|
||||
| Response body `model` | often `my-chat-model` | Often restamped to match the client; upstream id stays in config. |
|
||||
|
||||
### More examples (illustrative)
|
||||
|
||||
| Header | Example | Meaning |
|
||||
|--------|---------|---------|
|
||||
| `x-litellm-response-cost` | `0.000214` | This call (USD). |
|
||||
| `x-litellm-key-spend` | `12.847` | Key total after this call. |
|
||||
| `x-litellm-response-duration-ms` | `842.3` | Proxy end-to-end (ms). |
|
||||
| `x-litellm-overhead-duration-ms` | `15.1` | LiteLLM overhead (ms). |
|
||||
| `x-litellm-attempted-retries` | `0` | Retries. |
|
||||
| `x-litellm-attempted-fallbacks` | `1` | Fallbacks to another deployment. |
|
||||
| `x-litellm-call-id` | `019b2c4d-e5f6-7890-abcd-ef1234567890` | Logs / tracing. |
|
||||
| `x-litellm-version` | `1.55.3` | Version. |
|
||||
| `x-litellm-model-api-base` | `https://api.openai.com/v1` | Provider base (no query string). |
|
||||
|
||||
## Response headers from LLM providers
|
||||
|
||||
|
|
|
|||
|
|
@ -333,6 +333,67 @@ curl 'http://0.0.0.0:4000/key/generate' \
|
|||
}'
|
||||
```
|
||||
|
||||
#### **Set multiple budget windows on a key**
|
||||
|
||||
Apply multiple concurrent budget limits at different time scales on the same key — for example, cap a key at **$10/day** AND **$100/month**.
|
||||
|
||||
**When is this useful?**
|
||||
|
||||
A single `budget_duration` window can't prevent a bad day from burning your entire month. Multiple budget windows let you:
|
||||
|
||||
- Block a runaway usage spike within the day while still allowing normal monthly spend.
|
||||
- Give Claude Code rollouts a daily guardrail (`24h`) and a monthly ceiling (`30d`) so a single heavy session doesn't exhaust the whole month.
|
||||
- Layer fine-grained hourly limits for bursty workloads on top of a weekly cap.
|
||||
|
||||
:::info
|
||||
|
||||
See [User Budget docs](https://docs.litellm.ai/docs/proxy/users) for more on how budgets work across keys, teams, and users.
|
||||
|
||||
:::
|
||||
|
||||
**Via API**
|
||||
|
||||
Pass `budget_limits` as a list of `{budget_duration, max_budget}` objects:
|
||||
|
||||
```bash
|
||||
curl 'http://0.0.0.0:4000/key/generate' \
|
||||
--header 'Authorization: Bearer <your-master-key>' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data-raw '{
|
||||
"budget_limits": [
|
||||
{"budget_duration": "24h", "max_budget": 10},
|
||||
{"budget_duration": "30d", "max_budget": 100}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
Each window is tracked independently and resets on its own schedule:
|
||||
|
||||
| `budget_duration` | Resets |
|
||||
|---|---|
|
||||
| `1h` | Every hour |
|
||||
| `24h` | Daily at midnight UTC |
|
||||
| `7d` | Every Sunday at midnight UTC |
|
||||
| `30d` | 1st of every month at midnight UTC |
|
||||
|
||||
**Via Dashboard**
|
||||
|
||||
Open **Virtual Keys → Create Key → Optional Settings → Budget Windows**.
|
||||
|
||||
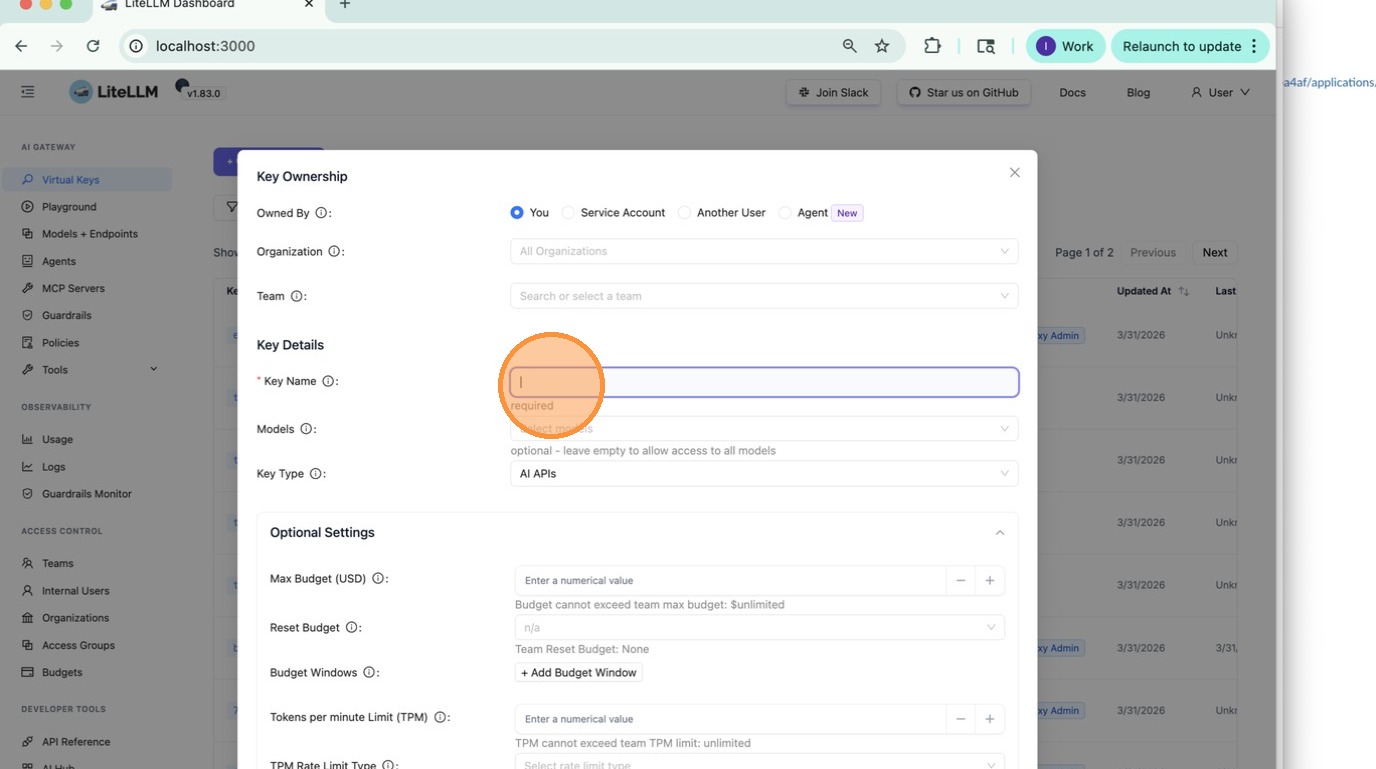
|
||||
|
||||
Click **+ Add Budget Window** to add a row, choose the period from the dropdown, and enter the spend cap.
|
||||
|
||||
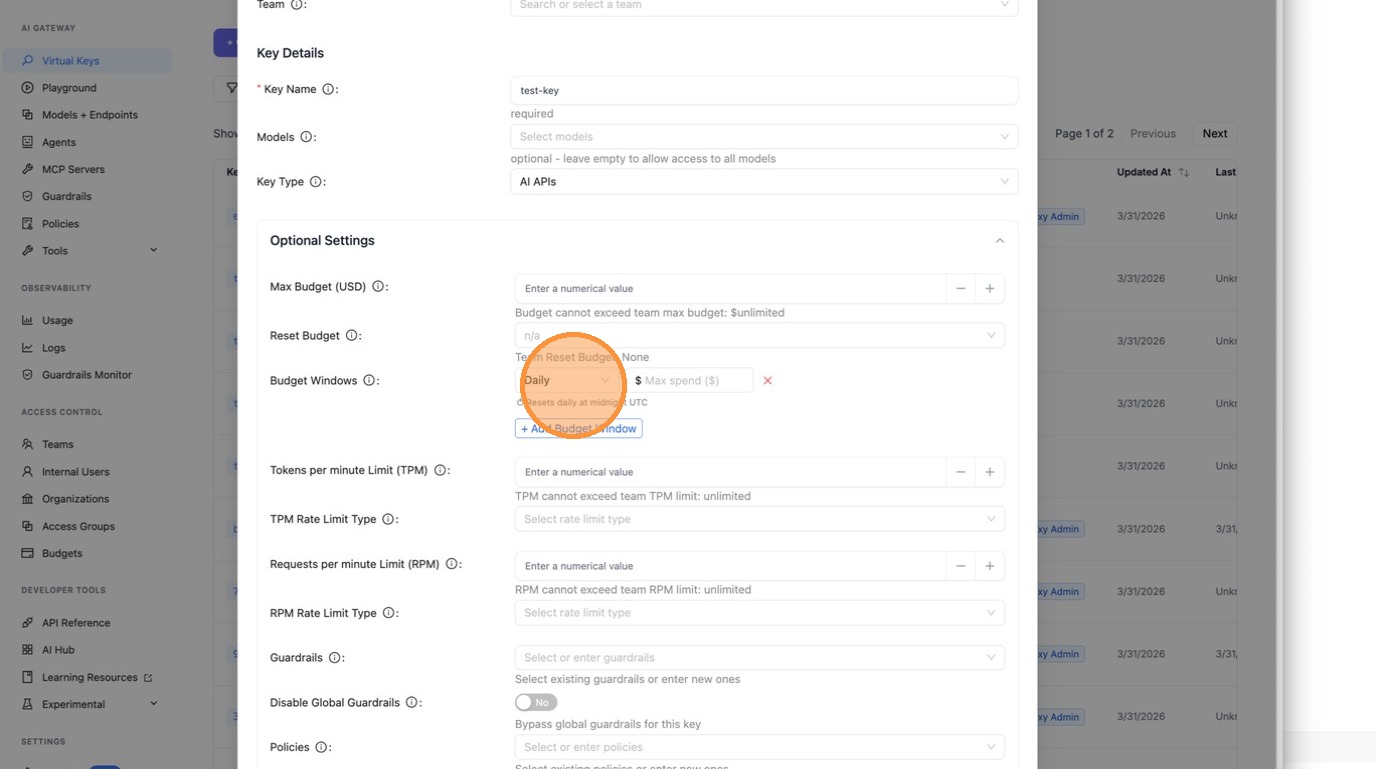
|
||||
|
||||
Add a second row for a different time period (e.g. monthly $100 on top of a daily $10).
|
||||
|
||||
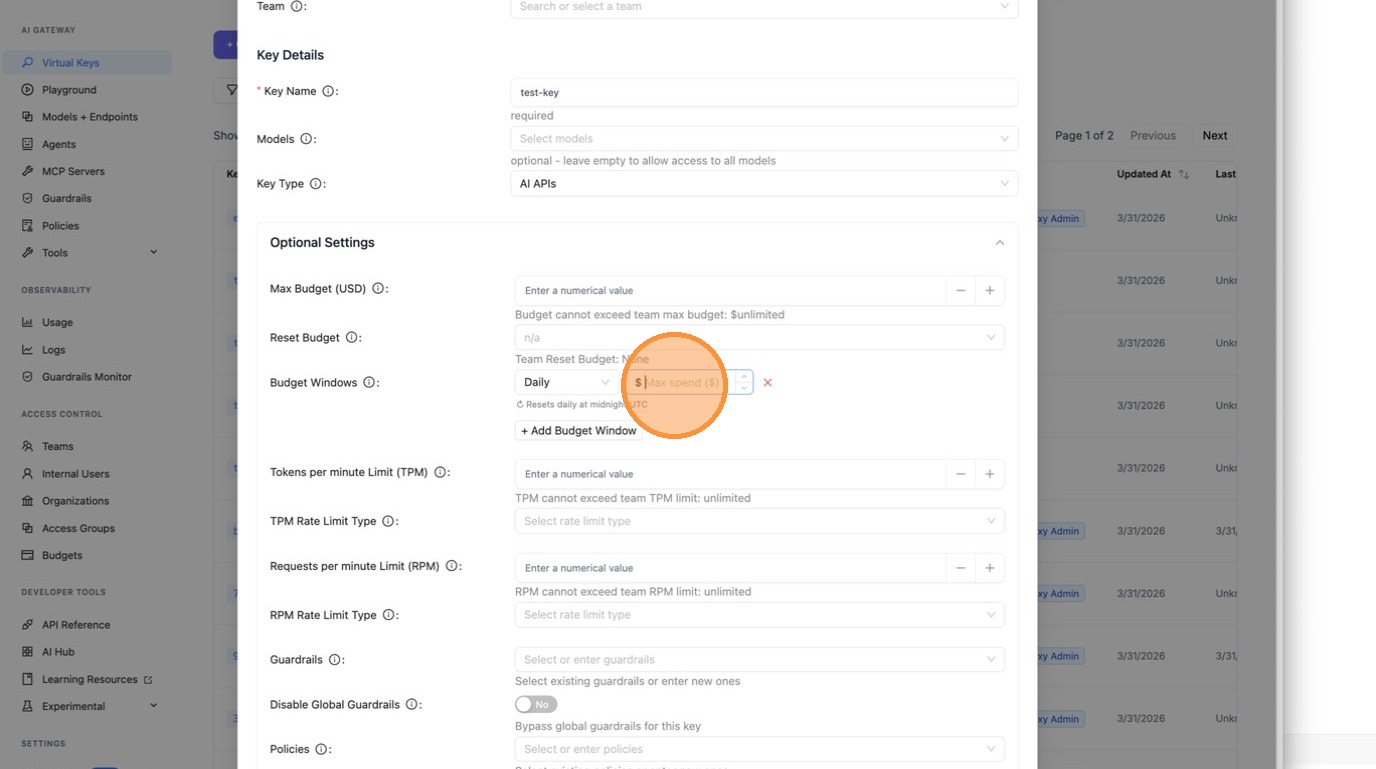
|
||||
|
||||
Each window shows the reset schedule below the input so it's always clear when spend resets.
|
||||
|
||||
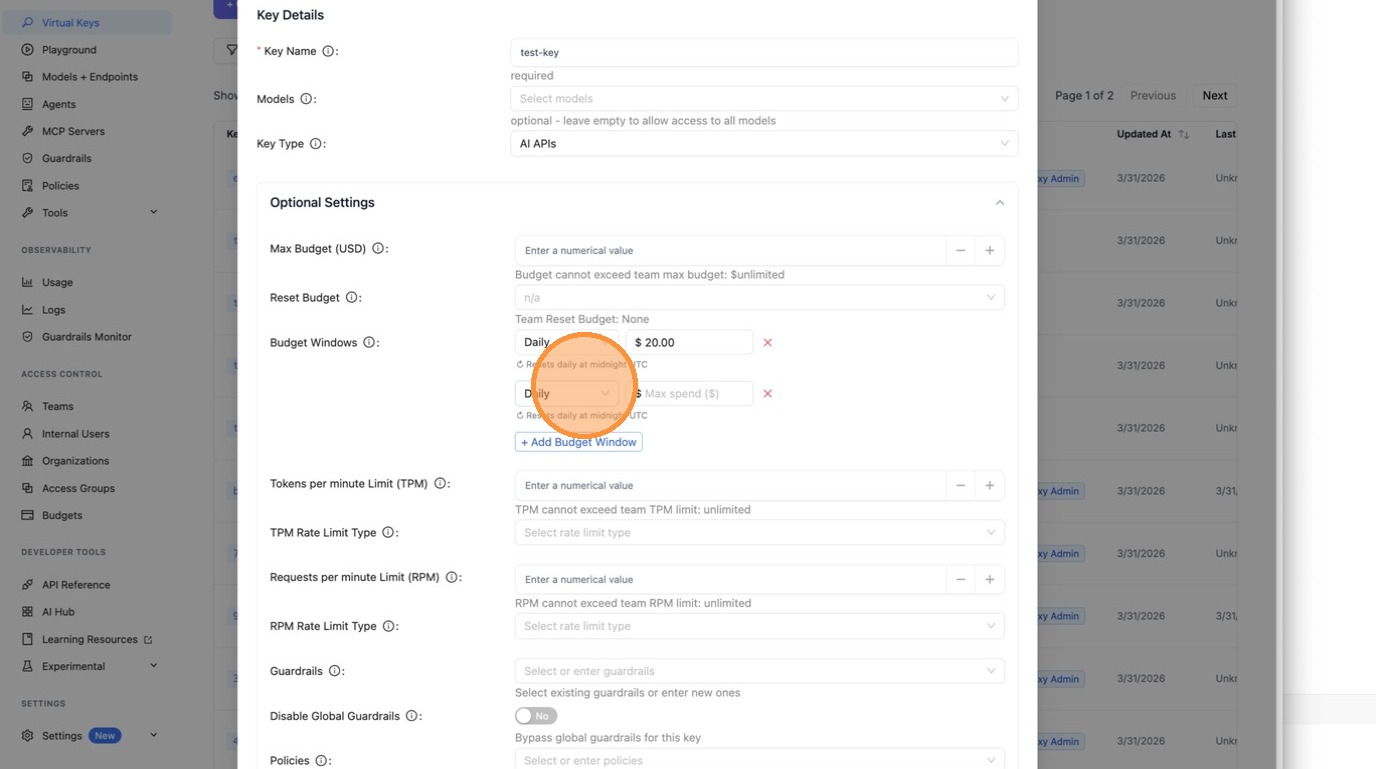
|
||||
|
||||
|
||||
### ✨ Virtual Key (Model Specific)
|
||||
|
||||
|
|
|
|||
|
|
@ -1505,6 +1505,84 @@ curl http://localhost:4000/v1/responses \
|
|||
|
||||
|
||||
|
||||
### Opt-in bridge for `openai/` models with custom `api_base`
|
||||
|
||||
If you're using an **OpenAI-compatible third-party provider** (e.g. llama.cpp, vLLM, LM Studio) via `openai/` prefix with a custom `api_base`, LiteLLM will normally forward `/responses` requests directly to that endpoint. If the provider only supports `/chat/completions`, the request will fail.
|
||||
|
||||
Use either of these to force the `/responses` → `/chat/completions` bridge:
|
||||
|
||||
1. **`use_chat_completions_api: true`** — makes it explicit that LiteLLM will call the provider’s chat-completions API.
|
||||
2. **`openai/chat_completions/<model_name>`** — same pattern as `responses/` on chat completions: the model id encodes the routing choice.
|
||||
|
||||
#### Python SDK Usage
|
||||
|
||||
```python showLineNumbers title="Force bridge for custom openai/ endpoint (flag)"
|
||||
import litellm
|
||||
|
||||
response = litellm.responses(
|
||||
model="openai/my-custom-model",
|
||||
input="Hello!",
|
||||
api_base="http://localhost:8080",
|
||||
api_key="fake-key",
|
||||
use_chat_completions_api=True,
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
Or encode it in the model id:
|
||||
|
||||
```python showLineNumbers title="Force bridge via openai/chat_completions/ model prefix"
|
||||
import litellm
|
||||
|
||||
response = litellm.responses(
|
||||
model="openai/chat_completions/my-custom-model",
|
||||
input="Hello!",
|
||||
api_base="http://localhost:8080",
|
||||
api_key="fake-key",
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
#### LiteLLM Proxy Usage
|
||||
|
||||
**Setup Config:**
|
||||
|
||||
```yaml showLineNumbers title="config.yaml — bridge for custom openai/ endpoint"
|
||||
model_list:
|
||||
- model_name: my-local-model
|
||||
litellm_params:
|
||||
model: openai/my-custom-model
|
||||
api_base: http://localhost:8080/v1
|
||||
api_key: fake-key
|
||||
use_chat_completions_api: true
|
||||
```
|
||||
|
||||
Alternatively set `model: openai/chat_completions/my-custom-model` instead of the flag.
|
||||
|
||||
**Start Proxy:**
|
||||
|
||||
```bash showLineNumbers title="Start LiteLLM Proxy"
|
||||
litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
**Make Request:**
|
||||
|
||||
```bash showLineNumbers title="Request via bridge"
|
||||
curl http://localhost:4000/v1/responses \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "my-local-model",
|
||||
"input": "Hello!"
|
||||
}'
|
||||
```
|
||||
|
||||
This is particularly useful when connecting clients that hardcode the `/responses` endpoint (e.g. OpenAI Codex CLI with `wire_api = "responses"`) to local or third-party OpenAI-compatible providers that only expose `/chat/completions`.
|
||||
|
||||
## Server-side compaction
|
||||
|
||||
For long-running conversations, you can enable **server-side compaction** so that when the rendered context size crosses a threshold, the server automatically runs compaction in-stream and emits a compaction item—no separate `POST /v1/responses/compact` call is required.
|
||||
|
|
|
|||
111
docs/my-website/docs/skills_gateway.md
Normal file
111
docs/my-website/docs/skills_gateway.md
Normal file
|
|
@ -0,0 +1,111 @@
|
|||
# Skills Gateway
|
||||
|
||||
<iframe width="840" height="500" src="https://www.loom.com/embed/cb74eb79df3e4c2b83a6efae54a589f9" frameborder="0" webkitallowfullscreen mozallowfullscreen allowfullscreen></iframe>
|
||||
|
||||
LiteLLM acts as a **Skills Registry** — a central place to register, manage, and discover Claude Code skills across your organization. Teams can publish skills once and have agents and developers find them through a single hub.
|
||||
|
||||
## How it works
|
||||
|
||||
```mermaid
|
||||
graph TD
|
||||
Dev["👨💻 Developer<br/>registers a skill<br/>(GitHub URL or subdir)"] -->|POST /claude-code/plugins| Proxy["LiteLLM Proxy<br/>(Skills Registry)"]
|
||||
|
||||
Admin["🔑 Admin<br/>publishes skill<br/>(marks as public)"] -->|enable via UI or API| Proxy
|
||||
|
||||
Proxy -->|GET /public/skill_hub| SkillHub["🗂️ Skill Hub<br/>(AI Hub → Skill Hub tab)"]
|
||||
Proxy -->|GET /claude-code/marketplace.json| Marketplace["📦 Claude Code<br/>Marketplace endpoint"]
|
||||
|
||||
SkillHub --> Human["🧑 Human<br/>browses & discovers skills<br/>in AI Hub UI"]
|
||||
Marketplace --> Agent["🤖 Agent / Claude Code<br/>installs skill with<br/>/plugin marketplace add <name>"]
|
||||
|
||||
style Proxy fill:#1a73e8,color:#fff
|
||||
style SkillHub fill:#e8f0fe,color:#1a73e8
|
||||
style Marketplace fill:#e8f0fe,color:#1a73e8
|
||||
```
|
||||
|
||||
## Quick start
|
||||
|
||||
### 1. Register a skill
|
||||
|
||||
Paste any GitHub URL into the Skills UI — LiteLLM auto-detects the source type and skill name.
|
||||
|
||||
```bash
|
||||
curl -X POST https://your-proxy/claude-code/plugins \
|
||||
-H "Authorization: Bearer $LITELLM_KEY" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"name": "grill-me",
|
||||
"source": {
|
||||
"source": "git-subdir",
|
||||
"url": "https://github.com/mattpocock/skills",
|
||||
"path": "grill-me"
|
||||
},
|
||||
"description": "Interview skill for relentless questioning",
|
||||
"domain": "Productivity",
|
||||
"namespace": "interviews"
|
||||
}'
|
||||
```
|
||||
|
||||
Skills nested in subdirectories (e.g. `github.com/org/repo/tree/main/skill-name`) are supported — LiteLLM parses the URL automatically in the UI.
|
||||
|
||||
### 2. Publish to hub
|
||||
|
||||
In the Admin UI: **AI Hub → Skill Hub → Select Skills to Make Public**.
|
||||
|
||||
Or via API:
|
||||
|
||||
```bash
|
||||
curl -X POST https://your-proxy/claude-code/plugins/grill-me/enable \
|
||||
-H "Authorization: Bearer $LITELLM_KEY"
|
||||
```
|
||||
|
||||
### 3. Browse the hub
|
||||
|
||||
Public skills appear at:
|
||||
- **Admin UI**: AI Hub → Skill Hub tab
|
||||
- **Public page**: `/ui/model_hub` → Skill Hub tab (no login required)
|
||||
- **API**: `GET /public/skill_hub`
|
||||
|
||||
### 4. Install in Claude Code
|
||||
|
||||
Point Claude Code at your proxy marketplace once:
|
||||
|
||||
```json title="~/.claude/settings.json"
|
||||
{
|
||||
"extraKnownMarketplaces": {
|
||||
"my-org": {
|
||||
"source": "url",
|
||||
"url": "https://your-proxy/claude-code/marketplace.json"
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Then install any skill:
|
||||
|
||||
```
|
||||
/plugin marketplace add grill-me
|
||||
```
|
||||
|
||||
## Skill fields
|
||||
|
||||
| Field | Description |
|
||||
|-------|-------------|
|
||||
| `name` | Unique skill identifier (used in `/plugin marketplace add`) |
|
||||
| `source` | Git source — `github`, `url`, or `git-subdir` |
|
||||
| `description` | Short description shown in the hub |
|
||||
| `domain` | Category for grouping (e.g. `Engineering`, `Productivity`) |
|
||||
| `namespace` | Subcategory within a domain (e.g. `quality`, `meetings`) |
|
||||
| `keywords` | Tags for search and filtering |
|
||||
| `version` | Semver string |
|
||||
|
||||
## API reference
|
||||
|
||||
| Endpoint | Auth | Description |
|
||||
|----------|------|-------------|
|
||||
| `POST /claude-code/plugins` | Required | Register a skill |
|
||||
| `GET /claude-code/plugins` | Required | List all skills (admin) |
|
||||
| `POST /claude-code/plugins/{name}/enable` | Required | Publish a skill |
|
||||
| `POST /claude-code/plugins/{name}/disable` | Required | Unpublish a skill |
|
||||
| `GET /public/skill_hub` | None | List public skills |
|
||||
| `GET /claude-code/marketplace.json` | None | Claude Code marketplace manifest |
|
||||
|
|
@ -35,6 +35,17 @@ By default, LiteLLM strips `x-api-key` from client requests for security. Settin
|
|||
|
||||
:::
|
||||
|
||||
:::tip Configure via UI instead of config.yaml
|
||||
|
||||
You can also complete this setup from the LiteLLM admin UI:
|
||||
|
||||
- Add the model via **Models → Add Model**, leaving the **API Key** field blank.
|
||||
- Enable the toggle at **Settings → UI Settings → "Forward LLM provider auth headers"**.
|
||||
|
||||
Both UI actions write to the database and override `config.yaml` at runtime.
|
||||
|
||||
:::
|
||||
|
||||
## Step 2: Create a LiteLLM Virtual Key
|
||||
|
||||
Create a virtual key in the LiteLLM UI or via API.
|
||||
|
|
|
|||
|
|
@ -8,6 +8,22 @@ Reduce costs by up to 90% by using LiteLLM to auto-inject prompt caching checkpo
|
|||
|
||||
<Image img={require('../../img/auto_prompt_caching.png')} style={{ width: '800px', height: 'auto' }} />
|
||||
|
||||
Supported Providers (`cache_control` marker):
|
||||
- Anthropic API (`anthropic/`)
|
||||
- AWS Bedrock - Claude (`bedrock/`)
|
||||
- Vertex AI - Claude and Gemini (`vertex_ai/`)
|
||||
- Google AI Studio - Gemini (`gemini/`)
|
||||
- Azure AI - Claude (`azure_ai/`)
|
||||
- OpenRouter - Claude, Gemini, MiniMax, GLM, z-ai routes (`openrouter/`)
|
||||
- Databricks - Claude (`databricks/`)
|
||||
- DashScope / Qwen (`dashscope/`)
|
||||
- MiniMax (`minimax/`)
|
||||
- Z.ai / GLM (`zai/`)
|
||||
|
||||
Provider Managed (automatic, no marker needed):
|
||||
- OpenAI (`openai/`)
|
||||
- DeepSeek (`deepseek/`)
|
||||
- xAI (`xai/`)
|
||||
|
||||
## How it works
|
||||
|
||||
|
|
|
|||
|
|
@ -187,6 +187,32 @@ const config = {
|
|||
},
|
||||
],
|
||||
|
||||
[
|
||||
'@signalwire/docusaurus-plugin-llms-txt',
|
||||
{
|
||||
markdown: {
|
||||
enableFiles: true,
|
||||
includeDocs: true,
|
||||
},
|
||||
llmsTxt: {
|
||||
enableLlmsFullTxt: true,
|
||||
includeDocs: true,
|
||||
},
|
||||
ui: {
|
||||
copyPageContent: {
|
||||
buttonLabel: 'Copy Page',
|
||||
actions: {
|
||||
viewMarkdown: true,
|
||||
ai: {
|
||||
chatGPT: true,
|
||||
claude: true,
|
||||
},
|
||||
},
|
||||
},
|
||||
},
|
||||
},
|
||||
],
|
||||
|
||||
() => ({
|
||||
name: 'cripchat',
|
||||
injectHtmlTags() {
|
||||
|
|
@ -239,7 +265,7 @@ const config = {
|
|||
],
|
||||
],
|
||||
|
||||
themes: ['@docusaurus/theme-mermaid'],
|
||||
themes: ['@docusaurus/theme-mermaid', '@signalwire/docusaurus-theme-llms-txt'],
|
||||
markdown: {
|
||||
mermaid: true,
|
||||
},
|
||||
|
|
|
|||
397
docs/my-website/package-lock.json
generated
397
docs/my-website/package-lock.json
generated
|
|
@ -15,6 +15,8 @@
|
|||
"@docusaurus/theme-mermaid": "3.8.1",
|
||||
"@inkeep/cxkit-docusaurus": "0.5.107",
|
||||
"@mdx-js/react": "3.1.1",
|
||||
"@signalwire/docusaurus-plugin-llms-txt": "2.0.0-alpha.7",
|
||||
"@signalwire/docusaurus-theme-llms-txt": "1.0.0-alpha.9",
|
||||
"clsx": "1.2.1",
|
||||
"prism-react-renderer": "1.3.5",
|
||||
"react": "18.3.1",
|
||||
|
|
@ -24,6 +26,7 @@
|
|||
},
|
||||
"devDependencies": {
|
||||
"@docusaurus/module-type-aliases": "3.8.1",
|
||||
"ajv": "^8.18.0",
|
||||
"dotenv": "16.6.1"
|
||||
},
|
||||
"engines": {
|
||||
|
|
@ -7140,6 +7143,72 @@
|
|||
"integrity": "sha512-RNiOoTPkptFtSVzQevY/yWtZwf/RxyVnPy/OcA9HBM3MlGDnBEYL5B41H0MTn0Uec8Hi+2qUtTfG2WWZBmMejQ==",
|
||||
"license": "BSD-3-Clause"
|
||||
},
|
||||
"node_modules/@signalwire/docusaurus-plugin-llms-txt": {
|
||||
"version": "2.0.0-alpha.7",
|
||||
"resolved": "https://registry.npmjs.org/@signalwire/docusaurus-plugin-llms-txt/-/docusaurus-plugin-llms-txt-2.0.0-alpha.7.tgz",
|
||||
"integrity": "sha512-v9EcYXVNvMydIWVIzI1H2iC4/BNdystE0jJAQIFu68SHy1a13dESz9hn5YJE9Izx18QPny1jhXym/3wEP9+8LA==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"fs-extra": "^11.0.0",
|
||||
"hast-util-select": "^6.0.4",
|
||||
"hast-util-to-html": "^9.0.5",
|
||||
"hast-util-to-string": "^3.0.1",
|
||||
"p-map": "^7.0.2",
|
||||
"rehype-parse": "^9",
|
||||
"rehype-remark": "^10",
|
||||
"remark-gfm": "^4",
|
||||
"remark-stringify": "^11",
|
||||
"string-width": "^5.0.0",
|
||||
"unified": "^11",
|
||||
"unist-util-visit": "^5"
|
||||
},
|
||||
"engines": {
|
||||
"node": ">=18.0.0"
|
||||
},
|
||||
"peerDependencies": {
|
||||
"@docusaurus/core": "^3.0.0"
|
||||
}
|
||||
},
|
||||
"node_modules/@signalwire/docusaurus-plugin-llms-txt/node_modules/p-map": {
|
||||
"version": "7.0.4",
|
||||
"resolved": "https://registry.npmjs.org/p-map/-/p-map-7.0.4.tgz",
|
||||
"integrity": "sha512-tkAQEw8ysMzmkhgw8k+1U/iPhWNhykKnSk4Rd5zLoPJCuJaGRPo6YposrZgaxHKzDHdDWWZvE/Sk7hsL2X/CpQ==",
|
||||
"license": "MIT",
|
||||
"engines": {
|
||||
"node": ">=18"
|
||||
},
|
||||
"funding": {
|
||||
"url": "https://github.com/sponsors/sindresorhus"
|
||||
}
|
||||
},
|
||||
"node_modules/@signalwire/docusaurus-theme-llms-txt": {
|
||||
"version": "1.0.0-alpha.9",
|
||||
"resolved": "https://registry.npmjs.org/@signalwire/docusaurus-theme-llms-txt/-/docusaurus-theme-llms-txt-1.0.0-alpha.9.tgz",
|
||||
"integrity": "sha512-ULCKEKkAUZVnLr8+ocR4tl7ogiiW13Hqtoo8SfNbgOyX1l4LN3a6j3/vxgc6qRYbgWlnqY3EPC7S3tenRsDjgQ==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@docusaurus/core": "^3.0.0",
|
||||
"@docusaurus/theme-common": "^3.0.0",
|
||||
"clsx": "^2.0.0",
|
||||
"react-icons": "^5.5.0"
|
||||
},
|
||||
"engines": {
|
||||
"node": ">=18.0.0"
|
||||
},
|
||||
"peerDependencies": {
|
||||
"react": "^18.0.0",
|
||||
"react-dom": "^18.0.0"
|
||||
}
|
||||
},
|
||||
"node_modules/@signalwire/docusaurus-theme-llms-txt/node_modules/clsx": {
|
||||
"version": "2.1.1",
|
||||
"resolved": "https://registry.npmjs.org/clsx/-/clsx-2.1.1.tgz",
|
||||
"integrity": "sha512-eYm0QWBtUrBWZWG0d386OGAw16Z995PiOVo2B7bjWSbHedGl5e0ZWaq65kOGgUSNesEIDkB9ISbTg/JK9dhCZA==",
|
||||
"license": "MIT",
|
||||
"engines": {
|
||||
"node": ">=6"
|
||||
}
|
||||
},
|
||||
"node_modules/@sinclair/typebox": {
|
||||
"version": "0.27.10",
|
||||
"resolved": "https://registry.npmjs.org/@sinclair/typebox/-/typebox-0.27.10.tgz",
|
||||
|
|
@ -8972,6 +9041,16 @@
|
|||
"integrity": "sha512-x+VAiMRL6UPkx+kudNvxTl6hB2XNNCG2r+7wixVfIYwu/2HKRXimwQyaumLjMveWvT2Hkd/cAJw+QBMfJ/EKVw==",
|
||||
"license": "MIT"
|
||||
},
|
||||
"node_modules/bcp-47-match": {
|
||||
"version": "2.0.3",
|
||||
"resolved": "https://registry.npmjs.org/bcp-47-match/-/bcp-47-match-2.0.3.tgz",
|
||||
"integrity": "sha512-JtTezzbAibu8G0R9op9zb3vcWZd9JF6M0xOYGPn0fNCd7wOpRB1mU2mH9T8gaBGbAAyIIVgB2G7xG0GP98zMAQ==",
|
||||
"license": "MIT",
|
||||
"funding": {
|
||||
"type": "github",
|
||||
"url": "https://github.com/sponsors/wooorm"
|
||||
}
|
||||
},
|
||||
"node_modules/big.js": {
|
||||
"version": "5.2.2",
|
||||
"resolved": "https://registry.npmjs.org/big.js/-/big.js-5.2.2.tgz",
|
||||
|
|
@ -10330,6 +10409,22 @@
|
|||
"url": "https://github.com/sponsors/fb55"
|
||||
}
|
||||
},
|
||||
"node_modules/css-selector-parser": {
|
||||
"version": "3.3.0",
|
||||
"resolved": "https://registry.npmjs.org/css-selector-parser/-/css-selector-parser-3.3.0.tgz",
|
||||
"integrity": "sha512-Y2asgMGFqJKF4fq4xHDSlFYIkeVfRsm69lQC1q9kbEsH5XtnINTMrweLkjYMeaUgiXBy/uvKeO/a1JHTNnmB2g==",
|
||||
"funding": [
|
||||
{
|
||||
"type": "github",
|
||||
"url": "https://github.com/sponsors/mdevils"
|
||||
},
|
||||
{
|
||||
"type": "patreon",
|
||||
"url": "https://patreon.com/mdevils"
|
||||
}
|
||||
],
|
||||
"license": "MIT"
|
||||
},
|
||||
"node_modules/css-tree": {
|
||||
"version": "3.2.1",
|
||||
"resolved": "https://registry.npmjs.org/css-tree/-/css-tree-3.2.1.tgz",
|
||||
|
|
@ -11291,6 +11386,19 @@
|
|||
"node": ">=8"
|
||||
}
|
||||
},
|
||||
"node_modules/direction": {
|
||||
"version": "2.0.1",
|
||||
"resolved": "https://registry.npmjs.org/direction/-/direction-2.0.1.tgz",
|
||||
"integrity": "sha512-9S6m9Sukh1cZNknO1CWAr2QAWsbKLafQiyM5gZ7VgXHeuaoUwffKN4q6NC4A/Mf9iiPlOXQEKW/Mv/mh9/3YFA==",
|
||||
"license": "MIT",
|
||||
"bin": {
|
||||
"direction": "cli.js"
|
||||
},
|
||||
"funding": {
|
||||
"type": "github",
|
||||
"url": "https://github.com/sponsors/wooorm"
|
||||
}
|
||||
},
|
||||
"node_modules/dns-packet": {
|
||||
"version": "5.6.1",
|
||||
"resolved": "https://registry.npmjs.org/dns-packet/-/dns-packet-5.6.1.tgz",
|
||||
|
|
@ -12812,6 +12920,38 @@
|
|||
"node": ">= 0.4"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-embedded": {
|
||||
"version": "3.0.0",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-embedded/-/hast-util-embedded-3.0.0.tgz",
|
||||
"integrity": "sha512-naH8sld4Pe2ep03qqULEtvYr7EjrLK2QHY8KJR6RJkTUjPGObe1vnx585uzem2hGra+s1q08DZZpfgDVYRbaXA==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/hast": "^3.0.0",
|
||||
"hast-util-is-element": "^3.0.0"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-from-html": {
|
||||
"version": "2.0.3",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-from-html/-/hast-util-from-html-2.0.3.tgz",
|
||||
"integrity": "sha512-CUSRHXyKjzHov8yKsQjGOElXy/3EKpyX56ELnkHH34vDVw1N1XSQ1ZcAvTyAPtGqLTuKP/uxM+aLkSPqF/EtMw==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/hast": "^3.0.0",
|
||||
"devlop": "^1.1.0",
|
||||
"hast-util-from-parse5": "^8.0.0",
|
||||
"parse5": "^7.0.0",
|
||||
"vfile": "^6.0.0",
|
||||
"vfile-message": "^4.0.0"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-from-parse5": {
|
||||
"version": "8.0.3",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-from-parse5/-/hast-util-from-parse5-8.0.3.tgz",
|
||||
|
|
@ -12832,6 +12972,62 @@
|
|||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-has-property": {
|
||||
"version": "3.0.0",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-has-property/-/hast-util-has-property-3.0.0.tgz",
|
||||
"integrity": "sha512-MNilsvEKLFpV604hwfhVStK0usFY/QmM5zX16bo7EjnAEGofr5YyI37kzopBlZJkHD4t887i+q/C8/tr5Q94cA==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/hast": "^3.0.0"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-is-body-ok-link": {
|
||||
"version": "3.0.1",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-is-body-ok-link/-/hast-util-is-body-ok-link-3.0.1.tgz",
|
||||
"integrity": "sha512-0qpnzOBLztXHbHQenVB8uNuxTnm/QBFUOmdOSsEn7GnBtyY07+ENTWVFBAnXd/zEgd9/SUG3lRY7hSIBWRgGpQ==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/hast": "^3.0.0"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-is-element": {
|
||||
"version": "3.0.0",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-is-element/-/hast-util-is-element-3.0.0.tgz",
|
||||
"integrity": "sha512-Val9mnv2IWpLbNPqc/pUem+a7Ipj2aHacCwgNfTiK0vJKl0LF+4Ba4+v1oPHFpf3bLYmreq0/l3Gud9S5OH42g==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/hast": "^3.0.0"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-minify-whitespace": {
|
||||
"version": "1.0.1",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-minify-whitespace/-/hast-util-minify-whitespace-1.0.1.tgz",
|
||||
"integrity": "sha512-L96fPOVpnclQE0xzdWb/D12VT5FabA7SnZOUMtL1DbXmYiHJMXZvFkIZfiMmTCNJHUeO2K9UYNXoVyfz+QHuOw==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/hast": "^3.0.0",
|
||||
"hast-util-embedded": "^3.0.0",
|
||||
"hast-util-is-element": "^3.0.0",
|
||||
"hast-util-whitespace": "^3.0.0",
|
||||
"unist-util-is": "^6.0.0"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-parse-selector": {
|
||||
"version": "4.0.0",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-parse-selector/-/hast-util-parse-selector-4.0.0.tgz",
|
||||
|
|
@ -12845,6 +13041,23 @@
|
|||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-phrasing": {
|
||||
"version": "3.0.1",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-phrasing/-/hast-util-phrasing-3.0.1.tgz",
|
||||
"integrity": "sha512-6h60VfI3uBQUxHqTyMymMZnEbNl1XmEGtOxxKYL7stY2o601COo62AWAYBQR9lZbYXYSBoxag8UpPRXK+9fqSQ==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/hast": "^3.0.0",
|
||||
"hast-util-embedded": "^3.0.0",
|
||||
"hast-util-has-property": "^3.0.0",
|
||||
"hast-util-is-body-ok-link": "^3.0.0",
|
||||
"hast-util-is-element": "^3.0.0"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-raw": {
|
||||
"version": "9.1.0",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-raw/-/hast-util-raw-9.1.0.tgz",
|
||||
|
|
@ -12870,6 +13083,33 @@
|
|||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-select": {
|
||||
"version": "6.0.4",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-select/-/hast-util-select-6.0.4.tgz",
|
||||
"integrity": "sha512-RqGS1ZgI0MwxLaKLDxjprynNzINEkRHY2i8ln4DDjgv9ZhcYVIHN9rlpiYsqtFwrgpYU361SyWDQcGNIBVu3lw==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/hast": "^3.0.0",
|
||||
"@types/unist": "^3.0.0",
|
||||
"bcp-47-match": "^2.0.0",
|
||||
"comma-separated-tokens": "^2.0.0",
|
||||
"css-selector-parser": "^3.0.0",
|
||||
"devlop": "^1.0.0",
|
||||
"direction": "^2.0.0",
|
||||
"hast-util-has-property": "^3.0.0",
|
||||
"hast-util-to-string": "^3.0.0",
|
||||
"hast-util-whitespace": "^3.0.0",
|
||||
"nth-check": "^2.0.0",
|
||||
"property-information": "^7.0.0",
|
||||
"space-separated-tokens": "^2.0.0",
|
||||
"unist-util-visit": "^5.0.0",
|
||||
"zwitch": "^2.0.0"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-to-estree": {
|
||||
"version": "3.1.3",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-to-estree/-/hast-util-to-estree-3.1.3.tgz",
|
||||
|
|
@ -12898,6 +13138,29 @@
|
|||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-to-html": {
|
||||
"version": "9.0.5",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-to-html/-/hast-util-to-html-9.0.5.tgz",
|
||||
"integrity": "sha512-OguPdidb+fbHQSU4Q4ZiLKnzWo8Wwsf5bZfbvu7//a9oTYoqD/fWpe96NuHkoS9h0ccGOTe0C4NGXdtS0iObOw==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/hast": "^3.0.0",
|
||||
"@types/unist": "^3.0.0",
|
||||
"ccount": "^2.0.0",
|
||||
"comma-separated-tokens": "^2.0.0",
|
||||
"hast-util-whitespace": "^3.0.0",
|
||||
"html-void-elements": "^3.0.0",
|
||||
"mdast-util-to-hast": "^13.0.0",
|
||||
"property-information": "^7.0.0",
|
||||
"space-separated-tokens": "^2.0.0",
|
||||
"stringify-entities": "^4.0.0",
|
||||
"zwitch": "^2.0.4"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-to-jsx-runtime": {
|
||||
"version": "2.3.6",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-to-jsx-runtime/-/hast-util-to-jsx-runtime-2.3.6.tgz",
|
||||
|
|
@ -12925,6 +13188,32 @@
|
|||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-to-mdast": {
|
||||
"version": "10.1.2",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-to-mdast/-/hast-util-to-mdast-10.1.2.tgz",
|
||||
"integrity": "sha512-FiCRI7NmOvM4y+f5w32jPRzcxDIz+PUqDwEqn1A+1q2cdp3B8Gx7aVrXORdOKjMNDQsD1ogOr896+0jJHW1EFQ==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/hast": "^3.0.0",
|
||||
"@types/mdast": "^4.0.0",
|
||||
"@ungap/structured-clone": "^1.0.0",
|
||||
"hast-util-phrasing": "^3.0.0",
|
||||
"hast-util-to-html": "^9.0.0",
|
||||
"hast-util-to-text": "^4.0.0",
|
||||
"hast-util-whitespace": "^3.0.0",
|
||||
"mdast-util-phrasing": "^4.0.0",
|
||||
"mdast-util-to-hast": "^13.0.0",
|
||||
"mdast-util-to-string": "^4.0.0",
|
||||
"rehype-minify-whitespace": "^6.0.0",
|
||||
"trim-trailing-lines": "^2.0.0",
|
||||
"unist-util-position": "^5.0.0",
|
||||
"unist-util-visit": "^5.0.0"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-to-parse5": {
|
||||
"version": "8.0.0",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-to-parse5/-/hast-util-to-parse5-8.0.0.tgz",
|
||||
|
|
@ -12954,6 +13243,35 @@
|
|||
"url": "https://github.com/sponsors/wooorm"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-to-string": {
|
||||
"version": "3.0.1",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-to-string/-/hast-util-to-string-3.0.1.tgz",
|
||||
"integrity": "sha512-XelQVTDWvqcl3axRfI0xSeoVKzyIFPwsAGSLIsKdJKQMXDYJS4WYrBNF/8J7RdhIcFI2BOHgAifggsvsxp/3+A==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/hast": "^3.0.0"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-to-text": {
|
||||
"version": "4.0.2",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-to-text/-/hast-util-to-text-4.0.2.tgz",
|
||||
"integrity": "sha512-KK6y/BN8lbaq654j7JgBydev7wuNMcID54lkRav1P0CaE1e47P72AWWPiGKXTJU271ooYzcvTAn/Zt0REnvc7A==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/hast": "^3.0.0",
|
||||
"@types/unist": "^3.0.0",
|
||||
"hast-util-is-element": "^3.0.0",
|
||||
"unist-util-find-after": "^5.0.0"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/hast-util-whitespace": {
|
||||
"version": "3.0.0",
|
||||
"resolved": "https://registry.npmjs.org/hast-util-whitespace/-/hast-util-whitespace-3.0.0.tgz",
|
||||
|
|
@ -19478,6 +19796,15 @@
|
|||
"react": "^16.8.0 || ^17 || ^18 || ^19"
|
||||
}
|
||||
},
|
||||
"node_modules/react-icons": {
|
||||
"version": "5.5.0",
|
||||
"resolved": "https://registry.npmjs.org/react-icons/-/react-icons-5.5.0.tgz",
|
||||
"integrity": "sha512-MEFcXdkP3dLo8uumGI5xN3lDFNsRtrjbOEKDLD7yv76v4wpnEq2Lt2qeHaQOr34I/wPN3s3+N08WkQ+CW37Xiw==",
|
||||
"license": "MIT",
|
||||
"peerDependencies": {
|
||||
"react": "*"
|
||||
}
|
||||
},
|
||||
"node_modules/react-is": {
|
||||
"version": "16.13.1",
|
||||
"resolved": "https://registry.npmjs.org/react-is/-/react-is-16.13.1.tgz",
|
||||
|
|
@ -19883,6 +20210,35 @@
|
|||
"regjsparser": "bin/parser"
|
||||
}
|
||||
},
|
||||
"node_modules/rehype-minify-whitespace": {
|
||||
"version": "6.0.2",
|
||||
"resolved": "https://registry.npmjs.org/rehype-minify-whitespace/-/rehype-minify-whitespace-6.0.2.tgz",
|
||||
"integrity": "sha512-Zk0pyQ06A3Lyxhe9vGtOtzz3Z0+qZ5+7icZ/PL/2x1SHPbKao5oB/g/rlc6BCTajqBb33JcOe71Ye1oFsuYbnw==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/hast": "^3.0.0",
|
||||
"hast-util-minify-whitespace": "^1.0.0"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/rehype-parse": {
|
||||
"version": "9.0.1",
|
||||
"resolved": "https://registry.npmjs.org/rehype-parse/-/rehype-parse-9.0.1.tgz",
|
||||
"integrity": "sha512-ksCzCD0Fgfh7trPDxr2rSylbwq9iYDkSn8TCDmEJ49ljEUBxDVCzCHv7QNzZOfODanX4+bWQ4WZqLCRWYLfhag==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/hast": "^3.0.0",
|
||||
"hast-util-from-html": "^2.0.0",
|
||||
"unified": "^11.0.0"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/rehype-raw": {
|
||||
"version": "7.0.0",
|
||||
"resolved": "https://registry.npmjs.org/rehype-raw/-/rehype-raw-7.0.0.tgz",
|
||||
|
|
@ -19913,6 +20269,23 @@
|
|||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/rehype-remark": {
|
||||
"version": "10.0.1",
|
||||
"resolved": "https://registry.npmjs.org/rehype-remark/-/rehype-remark-10.0.1.tgz",
|
||||
"integrity": "sha512-EmDndlb5NVwXGfUa4c9GPK+lXeItTilLhE6ADSaQuHr4JUlKw9MidzGzx4HpqZrNCt6vnHmEifXQiiA+CEnjYQ==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/hast": "^3.0.0",
|
||||
"@types/mdast": "^4.0.0",
|
||||
"hast-util-to-mdast": "^10.0.0",
|
||||
"unified": "^11.0.0",
|
||||
"vfile": "^6.0.0"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/relateurl": {
|
||||
"version": "0.2.7",
|
||||
"resolved": "https://registry.npmjs.org/relateurl/-/relateurl-0.2.7.tgz",
|
||||
|
|
@ -21641,6 +22014,16 @@
|
|||
"url": "https://github.com/sponsors/wooorm"
|
||||
}
|
||||
},
|
||||
"node_modules/trim-trailing-lines": {
|
||||
"version": "2.1.0",
|
||||
"resolved": "https://registry.npmjs.org/trim-trailing-lines/-/trim-trailing-lines-2.1.0.tgz",
|
||||
"integrity": "sha512-5UR5Biq4VlVOtzqkm2AZlgvSlDJtME46uV0br0gENbwN4l5+mMKT4b9gJKqWtuL2zAIqajGJGuvbCbcAJUZqBg==",
|
||||
"license": "MIT",
|
||||
"funding": {
|
||||
"type": "github",
|
||||
"url": "https://github.com/sponsors/wooorm"
|
||||
}
|
||||
},
|
||||
"node_modules/trough": {
|
||||
"version": "2.2.0",
|
||||
"resolved": "https://registry.npmjs.org/trough/-/trough-2.2.0.tgz",
|
||||
|
|
@ -21825,6 +22208,20 @@
|
|||
"url": "https://github.com/sponsors/sindresorhus"
|
||||
}
|
||||
},
|
||||
"node_modules/unist-util-find-after": {
|
||||
"version": "5.0.0",
|
||||
"resolved": "https://registry.npmjs.org/unist-util-find-after/-/unist-util-find-after-5.0.0.tgz",
|
||||
"integrity": "sha512-amQa0Ep2m6hE2g72AugUItjbuM8X8cGQnFoHk0pGfrFeT9GZhzN5SW8nRsiGKK7Aif4CrACPENkA6P/Lw6fHGQ==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/unist": "^3.0.0",
|
||||
"unist-util-is": "^6.0.0"
|
||||
},
|
||||
"funding": {
|
||||
"type": "opencollective",
|
||||
"url": "https://opencollective.com/unified"
|
||||
}
|
||||
},
|
||||
"node_modules/unist-util-is": {
|
||||
"version": "6.0.1",
|
||||
"resolved": "https://registry.npmjs.org/unist-util-is/-/unist-util-is-6.0.1.tgz",
|
||||
|
|
|
|||
|
|
@ -21,6 +21,8 @@
|
|||
"@docusaurus/theme-mermaid": "3.8.1",
|
||||
"@inkeep/cxkit-docusaurus": "0.5.107",
|
||||
"@mdx-js/react": "3.1.1",
|
||||
"@signalwire/docusaurus-plugin-llms-txt": "2.0.0-alpha.7",
|
||||
"@signalwire/docusaurus-theme-llms-txt": "1.0.0-alpha.9",
|
||||
"clsx": "1.2.1",
|
||||
"prism-react-renderer": "1.3.5",
|
||||
"react": "18.3.1",
|
||||
|
|
@ -30,6 +32,7 @@
|
|||
},
|
||||
"devDependencies": {
|
||||
"@docusaurus/module-type-aliases": "3.8.1",
|
||||
"ajv": "^8.18.0",
|
||||
"dotenv": "16.6.1"
|
||||
},
|
||||
"browserslist": {
|
||||
|
|
|
|||
|
|
@ -262,6 +262,9 @@ pip install litellm==1.82.3
|
|||
- **[OpenRouter](../../docs/providers/openrouter)**
|
||||
- Image edit support for OpenRouter models - [PR #22403](https://github.com/BerriAI/litellm/pull/22403)
|
||||
|
||||
- **[Google Gemini](../../docs/providers/gemini)**
|
||||
- Gemini 3 — no injected default `thinking_level` when `reasoning_effort` is omitted (matches Gemini API; Flash may default to `high` vs old `minimal`) — [Gemini 3 blog](../../blog/gemini_3)
|
||||
|
||||
- **[Google Vertex AI](../../docs/providers/vertex)**
|
||||
- VIDEO modality token usage tracking in `completion_tokens_details` - [PR #22550](https://github.com/BerriAI/litellm/pull/22550)
|
||||
|
||||
|
|
|
|||
|
|
@ -339,6 +339,13 @@ const sidebars = {
|
|||
},
|
||||
],
|
||||
},
|
||||
{
|
||||
type: "category",
|
||||
label: "Skills Gateway",
|
||||
items: [
|
||||
"skills_gateway",
|
||||
],
|
||||
},
|
||||
],
|
||||
},
|
||||
{
|
||||
|
|
@ -529,6 +536,7 @@ const sidebars = {
|
|||
description: "Modify requests, responses, and more",
|
||||
items: [
|
||||
"proxy/call_hooks",
|
||||
"proxy/agentic_loop_hook",
|
||||
"proxy/rules",
|
||||
]
|
||||
},
|
||||
|
|
@ -1052,6 +1060,7 @@ const sidebars = {
|
|||
},
|
||||
items: [
|
||||
"routing",
|
||||
"adaptive_router",
|
||||
"scheduler",
|
||||
"proxy/auto_routing",
|
||||
"proxy/load_balancing",
|
||||
|
|
|
|||
|
|
@ -27,6 +27,8 @@
|
|||
--ifm-font-size-base: 15px;
|
||||
--ifm-line-height-base: 1.65;
|
||||
--ifm-border-radius: 6px;
|
||||
/* Code fences: slightly more inset than Infima default (1rem), esp. next to bash left accent */
|
||||
--ifm-pre-padding: 1.25rem;
|
||||
/* Wider reading column — reduces excessive whitespace on large monitors */
|
||||
--ifm-container-width: 1380px;
|
||||
--ifm-container-width-xl: 1560px;
|
||||
|
|
@ -309,6 +311,38 @@ li.tabs__item--active {
|
|||
line-height: 1.6;
|
||||
}
|
||||
|
||||
/* Docusaurus line-number mode uses vertical-only padding on the inner wrapper; restore horizontal inset */
|
||||
.theme-code-block span[class*='codeLineContent'] {
|
||||
padding-left: var(--ifm-pre-padding);
|
||||
}
|
||||
|
||||
/* Doc + blog: both render under `article > .markdown`. Blog prose `.markdown code` and
|
||||
`pre:not(.prism-code) code` were zeroing inner padding on fenced blocks — match Infima/CodeBlock. */
|
||||
article .markdown pre:not(.prism-code) code {
|
||||
background: transparent;
|
||||
border: none;
|
||||
padding: 0;
|
||||
color: inherit;
|
||||
}
|
||||
|
||||
article .markdown pre.prism-code code[class*='codeBlockLinesWithNumbering'] {
|
||||
padding: var(--ifm-pre-padding) 0 !important;
|
||||
font-size: var(--ifm-code-font-size) !important;
|
||||
line-height: var(--ifm-pre-line-height) !important;
|
||||
background: transparent !important;
|
||||
border: none !important;
|
||||
color: inherit !important;
|
||||
}
|
||||
|
||||
article .markdown pre.prism-code code[class*='codeBlockLines']:not([class*='codeBlockLinesWithNumbering']) {
|
||||
padding: var(--ifm-pre-padding) !important;
|
||||
font-size: var(--ifm-code-font-size) !important;
|
||||
line-height: var(--ifm-pre-line-height) !important;
|
||||
background: transparent !important;
|
||||
border: none !important;
|
||||
color: inherit !important;
|
||||
}
|
||||
|
||||
[data-theme='dark'] .prism-code {
|
||||
border: 1px solid #21262d;
|
||||
}
|
||||
|
|
@ -881,13 +915,6 @@ video {
|
|||
box-shadow: 0 1px 3px rgba(0,0,0,0.06);
|
||||
}
|
||||
|
||||
.blog-wrapper article .markdown pre code {
|
||||
background: transparent;
|
||||
border: none;
|
||||
padding: 0;
|
||||
color: inherit;
|
||||
}
|
||||
|
||||
/* Hide tags section at bottom of blog posts */
|
||||
.blog-wrapper footer [class*='blogPostTags'],
|
||||
.blog-wrapper footer [class*='tags'] {
|
||||
|
|
|
|||
|
|
@ -3,6 +3,7 @@ Base class for sending emails to user after creating keys or invite links
|
|||
|
||||
"""
|
||||
|
||||
import html
|
||||
import json
|
||||
import os
|
||||
from typing import List, Literal, Optional
|
||||
|
|
@ -47,6 +48,15 @@ from litellm.secret_managers.main import get_secret_bool
|
|||
from litellm.types.integrations.slack_alerting import LITELLM_LOGO_URL
|
||||
|
||||
|
||||
def _parse_email_list(raw) -> List[str]:
|
||||
"""Parse emails from a list or comma-separated string."""
|
||||
if isinstance(raw, list):
|
||||
return [e.strip() for e in raw if isinstance(e, str) and e.strip()]
|
||||
elif isinstance(raw, str):
|
||||
return [e.strip() for e in raw.split(",") if e.strip()]
|
||||
return []
|
||||
|
||||
|
||||
class BaseEmailLogger(CustomLogger):
|
||||
DEFAULT_LITELLM_EMAIL = "notifications@alerts.litellm.ai"
|
||||
DEFAULT_SUPPORT_EMAIL = "support@berri.ai"
|
||||
|
|
@ -312,17 +322,22 @@ class BaseEmailLogger(CustomLogger):
|
|||
)
|
||||
pass
|
||||
|
||||
async def send_max_budget_alert_email(self, event: WebhookEvent):
|
||||
async def send_max_budget_alert_email(
|
||||
self,
|
||||
event: WebhookEvent,
|
||||
threshold_pct: Optional[int] = None,
|
||||
recipient_emails: Optional[List[str]] = None,
|
||||
):
|
||||
"""
|
||||
Send email to user when max budget alert threshold is reached
|
||||
"""
|
||||
email_params = await self._get_email_params(
|
||||
email_event=EmailEvent.max_budget_alert,
|
||||
user_id=event.user_id,
|
||||
user_email=event.user_email,
|
||||
event_message=event.event_message,
|
||||
)
|
||||
Send email to user when max budget alert threshold is reached.
|
||||
|
||||
Args:
|
||||
event: The webhook event with spend/budget info
|
||||
threshold_pct: Override percentage for multi-threshold alerts (e.g. 50, 75, 100).
|
||||
When None, uses EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE (old behavior).
|
||||
recipient_emails: Override recipient list for multi-threshold alerts.
|
||||
When None, resolves single owner email via _get_email_params (old behavior).
|
||||
"""
|
||||
verbose_proxy_logger.debug(
|
||||
f"send_max_budget_alert_email_event: {json.dumps(event.model_dump(exclude_none=True), indent=4, default=str)}"
|
||||
)
|
||||
|
|
@ -334,30 +349,67 @@ class BaseEmailLogger(CustomLogger):
|
|||
)
|
||||
|
||||
# Calculate percentage and alert threshold
|
||||
percentage = int(EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE * 100)
|
||||
percentage = threshold_pct if threshold_pct is not None else int(
|
||||
EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE * 100
|
||||
)
|
||||
threshold_fraction = percentage / 100.0
|
||||
alert_threshold_str = (
|
||||
f"${event.max_budget * EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE:.2f}"
|
||||
f"${event.max_budget * threshold_fraction:.2f}"
|
||||
if event.max_budget is not None
|
||||
else "N/A"
|
||||
)
|
||||
|
||||
email_html_content = MAX_BUDGET_ALERT_EMAIL_TEMPLATE.format(
|
||||
email_logo_url=email_params.logo_url,
|
||||
recipient_email=email_params.recipient_email,
|
||||
percentage=percentage,
|
||||
spend=spend_str,
|
||||
max_budget=max_budget_str,
|
||||
alert_threshold=alert_threshold_str,
|
||||
base_url=email_params.base_url,
|
||||
email_support_contact=email_params.support_contact,
|
||||
)
|
||||
await self.send_email(
|
||||
from_email=self.DEFAULT_LITELLM_EMAIL,
|
||||
to_email=[email_params.recipient_email],
|
||||
subject=email_params.subject,
|
||||
html_body=email_html_content,
|
||||
)
|
||||
pass
|
||||
if recipient_emails:
|
||||
# Multi-threshold path: batch send with generic key-based greeting
|
||||
email_params = await self._get_email_params(
|
||||
email_event=EmailEvent.max_budget_alert,
|
||||
user_id=event.user_id,
|
||||
user_email=event.user_email or recipient_emails[0],
|
||||
event_message=event.event_message,
|
||||
)
|
||||
greeting = html.escape(
|
||||
event.user_email or event.key_alias or event.token or ""
|
||||
)
|
||||
email_html_content = MAX_BUDGET_ALERT_EMAIL_TEMPLATE.format(
|
||||
email_logo_url=email_params.logo_url,
|
||||
recipient_email=greeting,
|
||||
percentage=percentage,
|
||||
spend=spend_str,
|
||||
max_budget=max_budget_str,
|
||||
alert_threshold=alert_threshold_str,
|
||||
base_url=email_params.base_url,
|
||||
email_support_contact=email_params.support_contact,
|
||||
)
|
||||
await self.send_email(
|
||||
from_email=self.DEFAULT_LITELLM_EMAIL,
|
||||
to_email=recipient_emails,
|
||||
subject=email_params.subject,
|
||||
html_body=email_html_content,
|
||||
)
|
||||
else:
|
||||
# Old path: single recipient resolved from user_id/user_email
|
||||
email_params = await self._get_email_params(
|
||||
email_event=EmailEvent.max_budget_alert,
|
||||
user_id=event.user_id,
|
||||
user_email=event.user_email,
|
||||
event_message=event.event_message,
|
||||
)
|
||||
email_html_content = MAX_BUDGET_ALERT_EMAIL_TEMPLATE.format(
|
||||
email_logo_url=email_params.logo_url,
|
||||
recipient_email=email_params.recipient_email,
|
||||
percentage=percentage,
|
||||
spend=spend_str,
|
||||
max_budget=max_budget_str,
|
||||
alert_threshold=alert_threshold_str,
|
||||
base_url=email_params.base_url,
|
||||
email_support_contact=email_params.support_contact,
|
||||
)
|
||||
await self.send_email(
|
||||
from_email=self.DEFAULT_LITELLM_EMAIL,
|
||||
to_email=[email_params.recipient_email],
|
||||
subject=email_params.subject,
|
||||
html_body=email_html_content,
|
||||
)
|
||||
|
||||
async def budget_alerts(
|
||||
self,
|
||||
|
|
@ -469,6 +521,13 @@ class BaseEmailLogger(CustomLogger):
|
|||
# For max_budget_alert, check if we've already sent an alert
|
||||
if type == "max_budget_alert":
|
||||
if user_info.max_budget is not None and user_info.spend is not None:
|
||||
if user_info.max_budget_alert_emails:
|
||||
# New path: multi-threshold alerts
|
||||
await self._handle_multi_threshold_max_budget_alert(
|
||||
user_info=user_info, _cache=_cache
|
||||
)
|
||||
return
|
||||
|
||||
alert_threshold = (
|
||||
user_info.max_budget * EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE
|
||||
)
|
||||
|
|
@ -527,6 +586,87 @@ class BaseEmailLogger(CustomLogger):
|
|||
)
|
||||
return
|
||||
|
||||
async def _handle_multi_threshold_max_budget_alert(
|
||||
self,
|
||||
user_info: CallInfo,
|
||||
_cache: DualCache,
|
||||
):
|
||||
"""
|
||||
Loop over configured thresholds in max_budget_alert_emails,
|
||||
check cache per threshold, and send to configured recipients.
|
||||
"""
|
||||
if not user_info.max_budget_alert_emails or user_info.max_budget is None:
|
||||
return
|
||||
|
||||
for threshold_str, raw_emails in user_info.max_budget_alert_emails.items():
|
||||
try:
|
||||
threshold_pct = int(threshold_str)
|
||||
except (ValueError, TypeError):
|
||||
continue
|
||||
|
||||
threshold_amount = user_info.max_budget * (threshold_pct / 100.0)
|
||||
if user_info.spend < threshold_amount:
|
||||
continue
|
||||
|
||||
_id = user_info.token or user_info.user_id or "default_id"
|
||||
_cache_key = (
|
||||
f"email_budget_alerts:max_budget_alert:{threshold_pct}:{_id}"
|
||||
)
|
||||
|
||||
result = await _cache.async_get_cache(key=_cache_key)
|
||||
if result is not None:
|
||||
continue
|
||||
|
||||
# Parse emails + auto-include owner
|
||||
emails = _parse_email_list(raw_emails)
|
||||
if user_info.user_email:
|
||||
emails.append(user_info.user_email)
|
||||
if not emails:
|
||||
verbose_proxy_logger.warning(
|
||||
"No recipients for %d%% threshold on key %s, skipping alert",
|
||||
threshold_pct,
|
||||
_id,
|
||||
)
|
||||
continue
|
||||
recipient_emails = list(set(emails))
|
||||
|
||||
event_message = f"Max Budget Alert - {threshold_pct}% of Maximum Budget Reached"
|
||||
webhook_event = WebhookEvent(
|
||||
event="max_budget_alert",
|
||||
event_message=event_message,
|
||||
spend=user_info.spend,
|
||||
max_budget=user_info.max_budget,
|
||||
soft_budget=user_info.soft_budget,
|
||||
token=user_info.token,
|
||||
customer_id=user_info.customer_id,
|
||||
user_id=user_info.user_id,
|
||||
team_id=user_info.team_id,
|
||||
team_alias=user_info.team_alias,
|
||||
organization_id=user_info.organization_id,
|
||||
user_email=user_info.user_email,
|
||||
key_alias=user_info.key_alias,
|
||||
projected_exceeded_date=user_info.projected_exceeded_date,
|
||||
projected_spend=user_info.projected_spend,
|
||||
event_group=user_info.event_group,
|
||||
)
|
||||
|
||||
try:
|
||||
await self.send_max_budget_alert_email(
|
||||
webhook_event,
|
||||
threshold_pct=threshold_pct,
|
||||
recipient_emails=recipient_emails,
|
||||
)
|
||||
await _cache.async_set_cache(
|
||||
key=_cache_key,
|
||||
value="SENT",
|
||||
ttl=EMAIL_BUDGET_ALERT_TTL,
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.error(
|
||||
f"Error sending multi-threshold max budget alert email for {threshold_pct}%: {e}",
|
||||
exc_info=True,
|
||||
)
|
||||
|
||||
async def _get_email_params(
|
||||
self,
|
||||
email_event: EmailEvent,
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
[project]
|
||||
name = "litellm-enterprise"
|
||||
version = "0.1.36"
|
||||
version = "0.1.38"
|
||||
description = "Package for LiteLLM Enterprise features"
|
||||
readme = "README.md"
|
||||
requires-python = ">=3.9"
|
||||
|
|
@ -25,7 +25,7 @@ required-version = "==0.10.9"
|
|||
module-root = ""
|
||||
|
||||
[tool.commitizen]
|
||||
version = "0.1.36"
|
||||
version = "0.1.38"
|
||||
version_files = [
|
||||
"pyproject.toml:^version",
|
||||
"../pyproject.toml:litellm-enterprise==",
|
||||
|
|
|
|||
|
|
@ -23,7 +23,8 @@ class JsonFormatter(logging.Formatter):
|
|||
def _is_json_enabled():
|
||||
try:
|
||||
import litellm
|
||||
return getattr(litellm, 'json_logs', False)
|
||||
|
||||
return getattr(litellm, "json_logs", False)
|
||||
except (ImportError, AttributeError):
|
||||
return os.getenv("JSON_LOGS", "false").lower() == "true"
|
||||
|
||||
|
|
@ -35,6 +36,8 @@ if not logger.handlers:
|
|||
if _is_json_enabled():
|
||||
handler.setFormatter(JsonFormatter())
|
||||
else:
|
||||
handler.setFormatter(logging.Formatter("%(asctime)s - %(name)s - %(levelname)s - %(message)s"))
|
||||
handler.setFormatter(
|
||||
logging.Formatter("%(asctime)s - %(name)s - %(levelname)s - %(message)s")
|
||||
)
|
||||
logger.addHandler(handler)
|
||||
logger.setLevel(logging.INFO)
|
||||
|
|
|
|||
|
|
@ -0,0 +1,5 @@
|
|||
-- AlterTable: add budget_limits column to LiteLLM_VerificationToken
|
||||
ALTER TABLE "LiteLLM_VerificationToken" ADD COLUMN IF NOT EXISTS "budget_limits" JSONB;
|
||||
|
||||
-- AlterTable: add budget_limits column to LiteLLM_TeamTable
|
||||
ALTER TABLE "LiteLLM_TeamTable" ADD COLUMN IF NOT EXISTS "budget_limits" JSONB;
|
||||
|
|
@ -0,0 +1,9 @@
|
|||
-- Add per-member model scope to LiteLLM_BudgetTable
|
||||
-- allowed_models: empty array = inherit team models; non-empty = enforce member-level restriction
|
||||
ALTER TABLE "LiteLLM_BudgetTable"
|
||||
ADD COLUMN IF NOT EXISTS "allowed_models" TEXT[] DEFAULT ARRAY[]::TEXT[];
|
||||
|
||||
-- Add default_team_member_models to LiteLLM_TeamTable
|
||||
-- Seeds allowed_models for newly added team members; empty = no per-member restriction
|
||||
ALTER TABLE "LiteLLM_TeamTable"
|
||||
ADD COLUMN IF NOT EXISTS "default_team_member_models" TEXT[] DEFAULT ARRAY[]::TEXT[];
|
||||
|
|
@ -0,0 +1,39 @@
|
|||
-- One row per (router, request_type, model). Hot path on every routing decision.
|
||||
CREATE TABLE "LiteLLM_AdaptiveRouterState" (
|
||||
router_name TEXT NOT NULL,
|
||||
request_type TEXT NOT NULL,
|
||||
model_name TEXT NOT NULL,
|
||||
alpha DOUBLE PRECISION NOT NULL,
|
||||
beta DOUBLE PRECISION NOT NULL,
|
||||
total_samples INTEGER NOT NULL DEFAULT 0,
|
||||
last_updated_at TIMESTAMP(3) NOT NULL DEFAULT CURRENT_TIMESTAMP,
|
||||
PRIMARY KEY (router_name, request_type, model_name)
|
||||
);
|
||||
|
||||
-- One row per (session, router, model). Updated per turn via the queue.
|
||||
CREATE TABLE "LiteLLM_AdaptiveRouterSession" (
|
||||
session_id TEXT NOT NULL,
|
||||
router_name TEXT NOT NULL,
|
||||
model_name TEXT NOT NULL,
|
||||
classified_type TEXT NOT NULL,
|
||||
misalignment_count INTEGER NOT NULL DEFAULT 0,
|
||||
stagnation_count INTEGER NOT NULL DEFAULT 0,
|
||||
disengagement_count INTEGER NOT NULL DEFAULT 0,
|
||||
satisfaction_count INTEGER NOT NULL DEFAULT 0,
|
||||
failure_count INTEGER NOT NULL DEFAULT 0,
|
||||
loop_count INTEGER NOT NULL DEFAULT 0,
|
||||
exhaustion_count INTEGER NOT NULL DEFAULT 0,
|
||||
last_user_content TEXT,
|
||||
last_assistant_content TEXT,
|
||||
tool_call_history JSONB NOT NULL DEFAULT '[]',
|
||||
pending_tool_calls JSONB NOT NULL DEFAULT '{}',
|
||||
turn_count INTEGER NOT NULL DEFAULT 0,
|
||||
last_processed_turn INTEGER NOT NULL DEFAULT -1,
|
||||
clean_credit_awarded BOOLEAN NOT NULL DEFAULT FALSE,
|
||||
terminal_status INTEGER,
|
||||
last_activity_at TIMESTAMP(3) NOT NULL DEFAULT CURRENT_TIMESTAMP,
|
||||
PRIMARY KEY (session_id, router_name, model_name)
|
||||
);
|
||||
|
||||
CREATE INDEX "idx_adaptive_router_session_activity"
|
||||
ON "LiteLLM_AdaptiveRouterSession" (last_activity_at);
|
||||
|
|
@ -0,0 +1,3 @@
|
|||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_TeamMembership" ADD COLUMN "total_spend" DOUBLE PRECISION NOT NULL DEFAULT 0.0;
|
||||
|
||||
|
|
@ -17,8 +17,9 @@ model LiteLLM_BudgetTable {
|
|||
tpm_limit BigInt?
|
||||
rpm_limit BigInt?
|
||||
model_max_budget Json?
|
||||
budget_duration String?
|
||||
budget_duration String?
|
||||
budget_reset_at DateTime?
|
||||
allowed_models String[] @default([]) // per-member model scope; empty = inherit team models
|
||||
created_at DateTime @default(now()) @map("created_at")
|
||||
created_by String
|
||||
updated_at DateTime @default(now()) @updatedAt @map("updated_at")
|
||||
|
|
@ -140,6 +141,8 @@ model LiteLLM_TeamTable {
|
|||
team_member_permissions String[] @default([])
|
||||
access_group_ids String[] @default([])
|
||||
policies String[] @default([])
|
||||
default_team_member_models String[] @default([]) // default allowed_models for newly added team members; empty = no per-member restriction
|
||||
budget_limits Json? // per-model budget limits for the team
|
||||
model_id Int? @unique // id for LiteLLM_ModelTable -> stores team-level model aliases
|
||||
allow_team_guardrail_config Boolean @default(false) // if true, team admin can configure guardrails for this team
|
||||
litellm_organization_table LiteLLM_OrganizationTable? @relation(fields: [organization_id], references: [organization_id])
|
||||
|
|
@ -401,6 +404,7 @@ model LiteLLM_VerificationToken {
|
|||
rotation_interval String? // How often to rotate (e.g., "30d", "90d")
|
||||
last_rotation_at DateTime? // When this key was last rotated
|
||||
key_rotation_at DateTime? // When this key should next be rotated
|
||||
budget_limits Json? // per-model budget limits for the key
|
||||
litellm_budget_table LiteLLM_BudgetTable? @relation(fields: [budget_id], references: [budget_id])
|
||||
litellm_organization_table LiteLLM_OrganizationTable? @relation(fields: [organization_id], references: [organization_id])
|
||||
litellm_project_table LiteLLM_ProjectTable? @relation(fields: [project_id], references: [project_id])
|
||||
|
|
@ -612,6 +616,7 @@ model LiteLLM_TeamMembership {
|
|||
user_id String
|
||||
team_id String
|
||||
spend Float @default(0.0)
|
||||
total_spend Float @default(0.0)
|
||||
budget_id String?
|
||||
litellm_budget_table LiteLLM_BudgetTable? @relation(fields: [budget_id], references: [budget_id])
|
||||
@@id([user_id, team_id])
|
||||
|
|
@ -1219,3 +1224,46 @@ model LiteLLM_ClaudeCodePluginTable {
|
|||
|
||||
@@map("LiteLLM_ClaudeCodePluginTable")
|
||||
}
|
||||
|
||||
// Per-(router, request_type, model) Beta posterior for the adaptive router.
|
||||
model LiteLLM_AdaptiveRouterState {
|
||||
router_name String
|
||||
request_type String
|
||||
model_name String
|
||||
alpha Float
|
||||
beta Float
|
||||
total_samples Int @default(0)
|
||||
last_updated_at DateTime @default(now()) @updatedAt
|
||||
|
||||
@@id([router_name, request_type, model_name])
|
||||
}
|
||||
|
||||
// Per-(session, router, model) signal counters for the adaptive router.
|
||||
model LiteLLM_AdaptiveRouterSession {
|
||||
session_id String
|
||||
router_name String
|
||||
model_name String
|
||||
classified_type String
|
||||
|
||||
misalignment_count Int @default(0)
|
||||
stagnation_count Int @default(0)
|
||||
disengagement_count Int @default(0)
|
||||
satisfaction_count Int @default(0)
|
||||
failure_count Int @default(0)
|
||||
loop_count Int @default(0)
|
||||
exhaustion_count Int @default(0)
|
||||
|
||||
last_user_content String?
|
||||
last_assistant_content String?
|
||||
tool_call_history Json @default("[]")
|
||||
pending_tool_calls Json @default("{}")
|
||||
|
||||
turn_count Int @default(0)
|
||||
last_processed_turn Int @default(-1)
|
||||
clean_credit_awarded Boolean @default(false)
|
||||
terminal_status Int?
|
||||
last_activity_at DateTime @default(now()) @updatedAt
|
||||
|
||||
@@id([session_id, router_name, model_name])
|
||||
@@index([last_activity_at], map: "idx_adaptive_router_session_activity")
|
||||
}
|
||||
|
|
|
|||
|
|
@ -4,8 +4,8 @@ import random
|
|||
import re
|
||||
import shutil
|
||||
import subprocess
|
||||
import tempfile
|
||||
import time
|
||||
from datetime import datetime
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
|
||||
|
|
@ -30,6 +30,26 @@ def _get_prisma_env() -> dict:
|
|||
return prisma_env
|
||||
|
||||
|
||||
_MIGRATION_TS_RE = re.compile(r"^(\d{14})_")
|
||||
|
||||
|
||||
def _migration_timestamp(name: str) -> int:
|
||||
"""Extract the leading `YYYYMMDDHHMMSS` timestamp from a migration name.
|
||||
|
||||
Returns 0 if the name doesn't match the Prisma pattern — unexpected-format
|
||||
entries sort as "oldest" and are treated as historical.
|
||||
"""
|
||||
m = _MIGRATION_TS_RE.match(name)
|
||||
return int(m.group(1)) if m else 0
|
||||
|
||||
|
||||
def _max_migration_timestamp(names) -> int:
|
||||
"""Max timestamp in a set/list of migration names (0 if empty)."""
|
||||
if not names:
|
||||
return 0
|
||||
return max(_migration_timestamp(n) for n in names)
|
||||
|
||||
|
||||
def _get_prisma_command() -> str:
|
||||
"""Get the Prisma command to use, bypassing Python wrapper in offline mode."""
|
||||
if str_to_bool(os.getenv("PRISMA_OFFLINE_MODE")):
|
||||
|
|
@ -256,21 +276,11 @@ class ProxyExtrasDBManager:
|
|||
if not database_url:
|
||||
logger.error("DATABASE_URL not set")
|
||||
return
|
||||
# Prefer DIRECT_URL for schema introspection — pooler URLs (e.g. neon -pooler)
|
||||
# do not support the extended query protocol required by prisma migrate diff.
|
||||
diff_url = os.getenv("DIRECT_URL") or database_url
|
||||
|
||||
diff_dir = (
|
||||
Path(migrations_dir)
|
||||
/ "migrations"
|
||||
/ f"{datetime.now().strftime('%Y%m%d%H%M%S')}_baseline_diff"
|
||||
)
|
||||
try:
|
||||
diff_dir.mkdir(parents=True, exist_ok=True)
|
||||
except Exception as e:
|
||||
if "Permission denied" in str(e):
|
||||
logger.warning(
|
||||
f"Permission denied - {e}\nunable to baseline db. Set LITELLM_MIGRATION_DIR environment variable to a writable directory to enable migrations."
|
||||
)
|
||||
return
|
||||
raise e
|
||||
diff_dir = Path(tempfile.mkdtemp(prefix="litellm_migration_diff_"))
|
||||
diff_sql_path = diff_dir / "migration.sql"
|
||||
|
||||
# 1. Generate migration SQL for the diff between DB and schema
|
||||
|
|
@ -283,7 +293,7 @@ class ProxyExtrasDBManager:
|
|||
"migrate",
|
||||
"diff",
|
||||
"--from-url",
|
||||
database_url,
|
||||
diff_url,
|
||||
"--to-schema-datamodel",
|
||||
schema_path,
|
||||
"--script",
|
||||
|
|
@ -300,7 +310,40 @@ class ProxyExtrasDBManager:
|
|||
|
||||
# check if the migration was created
|
||||
if not diff_sql_path.exists():
|
||||
logger.warning("Migration diff was not created")
|
||||
logger.warning(
|
||||
"Migration diff was not created (prisma migrate diff failed — "
|
||||
"likely a pooler URL). Falling back to direct SQL execution of "
|
||||
"each migration file."
|
||||
)
|
||||
# Fall back: run each migration SQL file directly via prisma db execute.
|
||||
# This works with pooler URLs (no schema introspection needed) and is
|
||||
# safe to re-run because migrations use IF NOT EXISTS / IF EXISTS guards.
|
||||
migration_files = sorted(Path(migrations_dir).glob("*/migration.sql"))
|
||||
for mig_file in migration_files:
|
||||
try:
|
||||
subprocess.run(
|
||||
[
|
||||
_get_prisma_command(),
|
||||
"db",
|
||||
"execute",
|
||||
"--file",
|
||||
str(mig_file),
|
||||
"--schema",
|
||||
schema_path,
|
||||
],
|
||||
timeout=60,
|
||||
check=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
env=_get_prisma_env(),
|
||||
)
|
||||
logger.info(f"Applied migration: {mig_file.parent.name}")
|
||||
except subprocess.CalledProcessError as e:
|
||||
logger.warning(
|
||||
f"Failed to apply migration {mig_file.parent.name}: {e.stderr}"
|
||||
)
|
||||
except subprocess.TimeoutExpired:
|
||||
logger.warning(f"Migration {mig_file.parent.name} timed out.")
|
||||
return
|
||||
logger.info(f"Migration diff created at {diff_sql_path}")
|
||||
|
||||
|
|
@ -360,18 +403,301 @@ class ProxyExtrasDBManager:
|
|||
)
|
||||
|
||||
@staticmethod
|
||||
def setup_database(use_migrate: bool = False) -> bool:
|
||||
def _strip_prisma_query_params(url: str) -> str:
|
||||
"""Remove Prisma-specific query params (connection_limit, pool_timeout,
|
||||
schema, etc.) from DATABASE_URL so psycopg can parse it."""
|
||||
from urllib.parse import urlparse, urlunparse, parse_qsl, urlencode
|
||||
|
||||
parsed = urlparse(url)
|
||||
if not parsed.query:
|
||||
return url
|
||||
libpq_params = {
|
||||
"sslmode",
|
||||
"sslcert",
|
||||
"sslkey",
|
||||
"sslrootcert",
|
||||
"sslpassword",
|
||||
"application_name",
|
||||
"connect_timeout",
|
||||
"client_encoding",
|
||||
"options",
|
||||
"service",
|
||||
"gssencmode",
|
||||
"krbsrvname",
|
||||
"target_session_attrs",
|
||||
}
|
||||
kept = [(k, v) for k, v in parse_qsl(parsed.query) if k in libpq_params]
|
||||
return urlunparse(parsed._replace(query=urlencode(kept)))
|
||||
|
||||
@staticmethod
|
||||
def _warn_if_db_ahead_of_head(migrations_dir: str) -> None:
|
||||
"""
|
||||
Log a warning if _prisma_migrations contains applied migrations with
|
||||
timestamps newer than every migration this build ships.
|
||||
|
||||
This is informational only for the v2 resolver — it tells the operator
|
||||
the DB was likely migrated by a newer deployment, which is usually a
|
||||
signal that this (older) version shouldn't run against it. We do NOT
|
||||
block startup: many users have weird _prisma_migrations state from
|
||||
prior thrashing bugs, and blocking them would be a breaking change.
|
||||
|
||||
Safe no-op if psycopg isn't installed or DB isn't reachable.
|
||||
"""
|
||||
database_url = os.getenv("DATABASE_URL")
|
||||
if not database_url:
|
||||
return
|
||||
|
||||
try:
|
||||
import psycopg
|
||||
except ImportError:
|
||||
return
|
||||
|
||||
cleaned_url = ProxyExtrasDBManager._strip_prisma_query_params(database_url)
|
||||
known = set(ProxyExtrasDBManager._get_migration_names(migrations_dir))
|
||||
|
||||
try:
|
||||
# autocommit=True keeps the SELECT outside a transaction. Without
|
||||
# it, psycopg3's `with conn` calls COMMIT on clean exit — which
|
||||
# fails after `UndefinedTable` (fresh DB) leaves the transaction
|
||||
# in an aborted state.
|
||||
with psycopg.connect(
|
||||
cleaned_url, connect_timeout=10, autocommit=True
|
||||
) as conn:
|
||||
try:
|
||||
rows = conn.execute(
|
||||
"SELECT migration_name FROM _prisma_migrations "
|
||||
"WHERE finished_at IS NOT NULL AND rolled_back_at IS NULL"
|
||||
).fetchall()
|
||||
except psycopg.errors.UndefinedTable:
|
||||
return
|
||||
except (psycopg.OperationalError, psycopg.DatabaseError):
|
||||
# Swallow connection failures AND any other DB-layer error
|
||||
# (e.g. InsufficientPrivilege if the runtime user lacks SELECT
|
||||
# on _prisma_migrations). This is an informational check —
|
||||
# never block startup on it.
|
||||
return
|
||||
|
||||
applied = {r[0] for r in rows}
|
||||
unknown = applied - known
|
||||
if not unknown:
|
||||
return
|
||||
|
||||
head_newest_ts = _max_migration_timestamp(known)
|
||||
hostile = {
|
||||
name for name in unknown if _migration_timestamp(name) > head_newest_ts
|
||||
}
|
||||
if not hostile:
|
||||
return
|
||||
|
||||
sorted_hostile = sorted(hostile)
|
||||
logger.warning(
|
||||
"Database has %d migration(s) applied that are NEWER than any "
|
||||
"migration this LiteLLM version ships. This usually means the "
|
||||
"database was migrated by a newer LiteLLM deployment. Some API "
|
||||
"endpoints may fail because this proxy's Prisma client does not "
|
||||
"know about those schema changes. Consider upgrading this "
|
||||
"deployment. Unknown: %s",
|
||||
len(hostile),
|
||||
", ".join(sorted_hostile[:5]) + (" ..." if len(sorted_hostile) > 5 else ""),
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def _setup_database_v2(use_migrate: bool) -> bool:
|
||||
"""
|
||||
v2 migration resolver (opt-in via --use_v2_migration_resolver).
|
||||
|
||||
Runs `prisma migrate deploy` and handles standard recovery paths
|
||||
(P3005 baseline, P3009/P3018 idempotent errors). Critically, it does
|
||||
NOT call `_resolve_all_migrations` — the diff-and-force recovery that
|
||||
caused schema thrashing when two LiteLLM versions contended for the
|
||||
same DB during rolling deploys.
|
||||
|
||||
Ahead-of-HEAD state (DB has migrations newer than this build ships)
|
||||
is logged as a warning, not a fatal error — users whose DBs got into
|
||||
weird shapes from the old thrashing should still be able to start.
|
||||
"""
|
||||
schema_path = ProxyExtrasDBManager._get_prisma_dir() + "/schema.prisma"
|
||||
migrations_dir = ProxyExtrasDBManager._get_prisma_dir()
|
||||
|
||||
if not use_migrate:
|
||||
# Preserve `prisma db push` path unchanged.
|
||||
original_dir = os.getcwd()
|
||||
os.chdir(migrations_dir)
|
||||
try:
|
||||
subprocess.run(
|
||||
[_get_prisma_command(), "db", "push", "--accept-data-loss"],
|
||||
timeout=60,
|
||||
check=True,
|
||||
env=_get_prisma_env(),
|
||||
)
|
||||
return True
|
||||
except (
|
||||
subprocess.CalledProcessError,
|
||||
subprocess.TimeoutExpired,
|
||||
) as e:
|
||||
# Re-raise as RuntimeError so proxy_cli.py's
|
||||
# `except RuntimeError` catches it and exits cleanly.
|
||||
raise RuntimeError(f"prisma db push failed.\n\nDetail: {e}") from e
|
||||
finally:
|
||||
os.chdir(original_dir)
|
||||
|
||||
# Informational — never blocks.
|
||||
ProxyExtrasDBManager._warn_if_db_ahead_of_head(migrations_dir)
|
||||
|
||||
original_dir = os.getcwd()
|
||||
os.chdir(migrations_dir)
|
||||
try:
|
||||
for attempt in range(4):
|
||||
try:
|
||||
result = subprocess.run(
|
||||
[_get_prisma_command(), "migrate", "deploy"],
|
||||
timeout=60,
|
||||
check=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
env=_get_prisma_env(),
|
||||
)
|
||||
logger.info(f"prisma migrate deploy stdout: {result.stdout}")
|
||||
return True
|
||||
|
||||
except subprocess.TimeoutExpired:
|
||||
logger.info(
|
||||
f"prisma migrate deploy attempt {attempt + 1} timed out, retrying"
|
||||
)
|
||||
time.sleep(random.randrange(5, 15))
|
||||
continue
|
||||
|
||||
except subprocess.CalledProcessError as e:
|
||||
stderr = e.stderr or ""
|
||||
|
||||
if "P3005" in stderr and "database schema is not empty" in stderr:
|
||||
logger.info(
|
||||
"Schema exists but no migrations ledger — creating baseline"
|
||||
)
|
||||
ProxyExtrasDBManager._create_baseline_migration(schema_path)
|
||||
continue
|
||||
|
||||
if "P3009" in stderr:
|
||||
migration_match = re.search(r"`(\d+_\S+?)`", stderr)
|
||||
if (
|
||||
migration_match
|
||||
and ProxyExtrasDBManager._is_idempotent_error(stderr)
|
||||
):
|
||||
name = migration_match.group(1)
|
||||
logger.info(
|
||||
f"Migration {name} failed idempotently — marking applied and retrying"
|
||||
)
|
||||
try:
|
||||
ProxyExtrasDBManager._roll_back_migration(name)
|
||||
except (
|
||||
subprocess.CalledProcessError,
|
||||
subprocess.TimeoutExpired,
|
||||
):
|
||||
pass # may already be rolled-back
|
||||
try:
|
||||
ProxyExtrasDBManager._resolve_specific_migration(name)
|
||||
except (
|
||||
subprocess.CalledProcessError,
|
||||
subprocess.TimeoutExpired,
|
||||
) as resolve_err:
|
||||
# We're already inside the outer
|
||||
# `except CalledProcessError` handler —
|
||||
# re-raising CalledProcessError from here
|
||||
# would escape as itself, bypassing
|
||||
# proxy_cli.py's `except RuntimeError`.
|
||||
raise RuntimeError(
|
||||
f"Failed to mark migration {name} as applied "
|
||||
f"after idempotent recovery. Manual "
|
||||
f"intervention may be required.\n\n"
|
||||
f"Detail: {resolve_err}"
|
||||
) from resolve_err
|
||||
continue
|
||||
raise RuntimeError(
|
||||
"Database migration failed and cannot be auto-recovered. "
|
||||
f"Manual intervention required.\n\nPrisma error:\n{stderr}"
|
||||
) from e
|
||||
|
||||
if "P3018" in stderr:
|
||||
if ProxyExtrasDBManager._is_permission_error(stderr):
|
||||
raise RuntimeError(
|
||||
"Database migration failed due to insufficient "
|
||||
"permissions. Please grant the required privileges "
|
||||
f"and retry.\n\nPrisma error:\n{stderr}"
|
||||
) from e
|
||||
|
||||
migration_match = re.search(
|
||||
r"Migration name: (\d+_\S+)", stderr
|
||||
)
|
||||
if (
|
||||
migration_match
|
||||
and ProxyExtrasDBManager._is_idempotent_error(stderr)
|
||||
):
|
||||
name = migration_match.group(1)
|
||||
logger.info(
|
||||
f"Migration {name} SQL hit idempotent error — marking applied and retrying"
|
||||
)
|
||||
try:
|
||||
ProxyExtrasDBManager._roll_back_migration(name)
|
||||
except (
|
||||
subprocess.CalledProcessError,
|
||||
subprocess.TimeoutExpired,
|
||||
):
|
||||
pass # may already be rolled-back
|
||||
try:
|
||||
ProxyExtrasDBManager._resolve_specific_migration(name)
|
||||
except (
|
||||
subprocess.CalledProcessError,
|
||||
subprocess.TimeoutExpired,
|
||||
) as resolve_err:
|
||||
raise RuntimeError(
|
||||
f"Failed to mark migration {name} as applied "
|
||||
f"after idempotent recovery. Manual "
|
||||
f"intervention may be required.\n\n"
|
||||
f"Detail: {resolve_err}"
|
||||
) from resolve_err
|
||||
continue
|
||||
|
||||
raise RuntimeError(
|
||||
"Database migration failed and cannot be auto-recovered. "
|
||||
f"Manual intervention required.\n\nPrisma error:\n{stderr}"
|
||||
) from e
|
||||
|
||||
raise RuntimeError(
|
||||
"Database migration failed and cannot be auto-recovered. "
|
||||
f"Manual intervention required.\n\nPrisma error:\n{stderr}"
|
||||
) from e
|
||||
|
||||
raise RuntimeError(
|
||||
"Database migration failed after 4 attempts (retry loop "
|
||||
"exhausted by timeouts or repeated idempotent-recovery "
|
||||
"continues). Check database connectivity, load, and "
|
||||
"_prisma_migrations ledger state."
|
||||
)
|
||||
finally:
|
||||
os.chdir(original_dir)
|
||||
|
||||
@staticmethod
|
||||
def setup_database(
|
||||
use_migrate: bool = False, use_v2_resolver: bool = False
|
||||
) -> bool:
|
||||
"""
|
||||
Set up the database using either prisma migrate or prisma db push
|
||||
Uses migrations from litellm-proxy-extras package
|
||||
|
||||
Args:
|
||||
schema_path (str): Path to the Prisma schema file
|
||||
use_migrate (bool): Whether to use prisma migrate instead of db push
|
||||
use_migrate: Whether to use prisma migrate instead of db push
|
||||
use_v2_resolver: Opt into the v2 migration resolver (safer during
|
||||
rolling deploys; does not run the diff-and-force recovery
|
||||
that causes schema thrashing). Defaults to False for
|
||||
backwards compatibility.
|
||||
|
||||
Returns:
|
||||
bool: True if setup was successful, False otherwise
|
||||
"""
|
||||
if use_v2_resolver:
|
||||
logger.info("Using v2 migration resolver (--use_v2_migration_resolver)")
|
||||
return ProxyExtrasDBManager._setup_database_v2(use_migrate=use_migrate)
|
||||
|
||||
schema_path = ProxyExtrasDBManager._get_prisma_dir() + "/schema.prisma"
|
||||
for attempt in range(4):
|
||||
original_dir = os.getcwd()
|
||||
|
|
@ -395,6 +721,14 @@ class ProxyExtrasDBManager:
|
|||
|
||||
logger.info("prisma migrate deploy completed")
|
||||
|
||||
# Skip sanity check when deploy reports no pending migrations —
|
||||
# DB already matches schema, no drift to correct.
|
||||
if "No pending migrations to apply" in result.stdout:
|
||||
logger.info(
|
||||
"No pending migrations — skipping post-migration sanity check"
|
||||
)
|
||||
return True
|
||||
|
||||
# Run sanity check to ensure DB matches schema
|
||||
logger.info("Running post-migration sanity check...")
|
||||
ProxyExtrasDBManager._resolve_all_migrations(
|
||||
|
|
@ -419,7 +753,10 @@ class ProxyExtrasDBManager:
|
|||
ProxyExtrasDBManager._roll_back_migration(
|
||||
failed_migration
|
||||
)
|
||||
except (subprocess.CalledProcessError, subprocess.TimeoutExpired) as rollback_err:
|
||||
except (
|
||||
subprocess.CalledProcessError,
|
||||
subprocess.TimeoutExpired,
|
||||
) as rollback_err:
|
||||
logger.warning(
|
||||
f"Failed to roll back migration {failed_migration}: {rollback_err}. "
|
||||
f"It may already be in a rolled-back state."
|
||||
|
|
@ -431,10 +768,19 @@ class ProxyExtrasDBManager:
|
|||
logger.info(
|
||||
f"✅ Migration {failed_migration} resolved, retrying to apply remaining migrations"
|
||||
)
|
||||
except (subprocess.CalledProcessError, subprocess.TimeoutExpired) as resolve_err:
|
||||
except (
|
||||
subprocess.CalledProcessError,
|
||||
subprocess.TimeoutExpired,
|
||||
) as resolve_err:
|
||||
logger.warning(
|
||||
f"Failed to resolve migration {failed_migration}: {resolve_err}"
|
||||
)
|
||||
# Apply any schema drift not covered by the marked-as-applied migration
|
||||
ProxyExtrasDBManager._resolve_all_migrations(
|
||||
migrations_dir,
|
||||
schema_path,
|
||||
mark_all_applied=False,
|
||||
)
|
||||
else:
|
||||
logger.info(
|
||||
f"Found failed migration: {failed_migration}, marking as rolled back"
|
||||
|
|
@ -531,7 +877,10 @@ class ProxyExtrasDBManager:
|
|||
ProxyExtrasDBManager._roll_back_migration(
|
||||
migration_name
|
||||
)
|
||||
except (subprocess.CalledProcessError, subprocess.TimeoutExpired) as rollback_err:
|
||||
except (
|
||||
subprocess.CalledProcessError,
|
||||
subprocess.TimeoutExpired,
|
||||
) as rollback_err:
|
||||
logger.warning(
|
||||
f"Failed to roll back migration {migration_name}: {rollback_err}. "
|
||||
f"It may already be in a rolled-back state."
|
||||
|
|
@ -548,10 +897,19 @@ class ProxyExtrasDBManager:
|
|||
f"✅ Migration {migration_name} resolved, "
|
||||
f"retrying to apply remaining migrations"
|
||||
)
|
||||
except (subprocess.CalledProcessError, subprocess.TimeoutExpired) as resolve_err:
|
||||
except (
|
||||
subprocess.CalledProcessError,
|
||||
subprocess.TimeoutExpired,
|
||||
) as resolve_err:
|
||||
logger.warning(
|
||||
f"Failed to resolve migration {migration_name}: {resolve_err}"
|
||||
)
|
||||
# Apply any schema drift not covered by the marked-as-applied migration
|
||||
ProxyExtrasDBManager._resolve_all_migrations(
|
||||
migrations_dir,
|
||||
schema_path,
|
||||
mark_all_applied=False,
|
||||
)
|
||||
else:
|
||||
# Unknown P3018 error - log and re-raise for safety
|
||||
logger.warning(
|
||||
|
|
|
|||
|
|
@ -2,6 +2,8 @@
|
|||
|
||||
This is a runbook for creating and running database migrations for the LiteLLM proxy. For use for litellm engineers only.
|
||||
|
||||
> **AI AGENTS / ASSISTANTS:** If the script refuses with either a "STALE BRANCH" or "DESTRUCTIVE MIGRATION DETECTED" error, **do NOT** bypass it on your own (no `git rebase`, no `--skip-freshness-check`, no `--allow-destructive`). Surface the error to the human operator and wait for their explicit confirmation. See the [Branch freshness](#branch-freshness-check) and [Destructive migrations](#destructive-migrations-drop-column--drop-table) sections below.
|
||||
|
||||
## Step 0: Sync All `schema.prisma` Files
|
||||
|
||||
Before doing anything else, make sure all `schema.prisma` files in the repo are in sync. There are multiple copies that must match:
|
||||
|
|
@ -46,10 +48,50 @@ uv run --with testing.postgresql python ci_cd/run_migration.py "your_migration_n
|
|||
|
||||
## What It Does
|
||||
|
||||
1. Creates temp PostgreSQL DB
|
||||
2. Applies existing migrations
|
||||
3. Compares with `schema.prisma`
|
||||
4. Generates new migration if changes found
|
||||
1. **Verifies the current branch is up to date with `origin/litellm_internal_staging`** (see [Branch freshness](#branch-freshness-check))
|
||||
2. Creates temp PostgreSQL DB
|
||||
3. Applies existing migrations
|
||||
4. Compares with `schema.prisma`
|
||||
5. Generates new migration if changes found
|
||||
6. **Refuses to write if the generated SQL contains `DROP COLUMN`, `DROP TABLE`, or `DROP INDEX`**, unless `--allow-destructive` is passed
|
||||
|
||||
## Branch Freshness Check
|
||||
|
||||
Before generating anything, `run_migration.py` runs `git fetch origin <base>` and refuses to proceed if `HEAD` is behind `origin/<base>`. Default base is `litellm_internal_staging` (the branch PRs target). A previous incident saw a stale branch silently drop production columns; freshness is the first-line defense.
|
||||
|
||||
Flags:
|
||||
|
||||
- `--base-branch <name>` — check against a different base (e.g. `main`). Default is `litellm_internal_staging`.
|
||||
- `--skip-freshness-check` — bypass entirely. Only for intentional migrations against an older base.
|
||||
|
||||
When the guard fires:
|
||||
|
||||
1. Update your branch:
|
||||
|
||||
```bash
|
||||
git fetch origin && git rebase origin/litellm_internal_staging
|
||||
# or git merge origin/litellm_internal_staging — whichever matches your workflow
|
||||
```
|
||||
2. Re-run `run_migration.py`.
|
||||
|
||||
> **AI AGENTS / ASSISTANTS:** Do **not** auto-rebase or auto-pass `--skip-freshness-check`. A bad conflict resolution during rebase can itself drop the human's in-progress schema edits. Surface the error and wait for explicit confirmation.
|
||||
|
||||
## Destructive Migrations (DROP COLUMN / DROP TABLE / DROP INDEX)
|
||||
|
||||
If the generated diff contains `DROP COLUMN`, `DROP TABLE`, or `DROP INDEX`, `run_migration.py` exits non-zero and refuses to write the migration file. A previous incident saw newly-added columns silently dropped by a stale branch and merged to main — this guard exists to prevent a repeat.
|
||||
|
||||
When the guard fires:
|
||||
|
||||
1. Run `git fetch origin && git status` — confirm your branch is up to date with the base branch.
|
||||
2. Re-check all `schema.prisma` files are in sync (Step 0).
|
||||
3. Review EACH `DROP` statement printed in the error — is it actually intended?
|
||||
4. Only if the drops are genuinely intentional, re-run with the flag:
|
||||
|
||||
```bash
|
||||
uv run --with testing.postgresql python ci_cd/run_migration.py "your_migration_name" --allow-destructive
|
||||
```
|
||||
|
||||
> **AI AGENTS / ASSISTANTS:** Do **not** automatically re-run the command with `--allow-destructive`. If the guard fires while you are driving the runbook for a human, stop, show them the error, and wait for their explicit confirmation before passing the flag. Auto-passing `--allow-destructive` is the exact failure mode this guard exists to prevent.
|
||||
|
||||
## Common Fixes
|
||||
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
[project]
|
||||
name = "litellm-proxy-extras"
|
||||
version = "0.4.66"
|
||||
version = "0.4.68"
|
||||
description = "Additional files for the LiteLLM Proxy. Reduces the size of the main litellm package."
|
||||
readme = "README.md"
|
||||
requires-python = ">=3.9"
|
||||
|
|
@ -25,7 +25,7 @@ required-version = "==0.10.9"
|
|||
module-root = ""
|
||||
|
||||
[tool.commitizen]
|
||||
version = "0.4.66"
|
||||
version = "0.4.68"
|
||||
version_files = [
|
||||
"pyproject.toml:^version",
|
||||
"../pyproject.toml:litellm-proxy-extras==",
|
||||
|
|
|
|||
242
litellm-proxy-extras/tests/test_setup_database_fail_fast.py
Normal file
242
litellm-proxy-extras/tests/test_setup_database_fail_fast.py
Normal file
|
|
@ -0,0 +1,242 @@
|
|||
"""Regression tests for ProxyExtrasDBManager v2 migration resolver.
|
||||
|
||||
The v2 resolver is opt-in via `--use_v2_migration_resolver` / the
|
||||
`use_v2_resolver=True` kwarg. These tests exercise the v2 path; the v1
|
||||
(default) behavior is unchanged from pre-fix.
|
||||
"""
|
||||
|
||||
import subprocess
|
||||
from unittest.mock import patch
|
||||
|
||||
import pytest
|
||||
|
||||
from litellm_proxy_extras.utils import (
|
||||
ProxyExtrasDBManager,
|
||||
_max_migration_timestamp,
|
||||
_migration_timestamp,
|
||||
)
|
||||
|
||||
|
||||
def _fake_migrate_deploy_failure(returncode: int, stderr: str):
|
||||
def _run(*args, **kwargs):
|
||||
raise subprocess.CalledProcessError(
|
||||
returncode=returncode,
|
||||
cmd=args[0],
|
||||
stderr=stderr,
|
||||
output="",
|
||||
)
|
||||
|
||||
return _run
|
||||
|
||||
|
||||
def test_v2_p3018_permission_error_raises_runtime_error(monkeypatch, tmp_path):
|
||||
"""v2: a permission failure during migrate deploy raises RuntimeError."""
|
||||
monkeypatch.setenv("DATABASE_URL", "postgresql://u:p@localhost:9/x")
|
||||
monkeypatch.setattr(
|
||||
ProxyExtrasDBManager, "_warn_if_db_ahead_of_head", lambda _: None
|
||||
)
|
||||
monkeypatch.setattr(ProxyExtrasDBManager, "_get_prisma_dir", lambda: str(tmp_path))
|
||||
(tmp_path / "schema.prisma").write_text("// stub")
|
||||
|
||||
stderr = (
|
||||
"Error: P3018\nMigration name: 20250326162113_baseline\n"
|
||||
"Database error code: 42501\npermission denied for schema public"
|
||||
)
|
||||
with patch("subprocess.run", side_effect=_fake_migrate_deploy_failure(1, stderr)):
|
||||
with pytest.raises(RuntimeError, match="permission"):
|
||||
ProxyExtrasDBManager.setup_database(use_migrate=True, use_v2_resolver=True)
|
||||
|
||||
|
||||
def test_v2_non_idempotent_p3009_raises_runtime_error(monkeypatch, tmp_path):
|
||||
"""v2: a non-idempotent migration failure raises (no silent recovery)."""
|
||||
monkeypatch.setenv("DATABASE_URL", "postgresql://u:p@localhost:9/x")
|
||||
monkeypatch.setattr(
|
||||
ProxyExtrasDBManager, "_warn_if_db_ahead_of_head", lambda _: None
|
||||
)
|
||||
monkeypatch.setattr(ProxyExtrasDBManager, "_get_prisma_dir", lambda: str(tmp_path))
|
||||
(tmp_path / "schema.prisma").write_text("// stub")
|
||||
|
||||
stderr = (
|
||||
"Error: P3009\nMigration `20260101000000_genuinely_broken` failed\n"
|
||||
'Reason: syntax error at or near "BRKN" LINE 42'
|
||||
)
|
||||
with patch("subprocess.run", side_effect=_fake_migrate_deploy_failure(1, stderr)):
|
||||
with pytest.raises(RuntimeError, match="cannot be auto-recovered"):
|
||||
ProxyExtrasDBManager.setup_database(use_migrate=True, use_v2_resolver=True)
|
||||
|
||||
|
||||
def test_strip_prisma_query_params_removes_connection_limit():
|
||||
"""DATABASE_URLs with Prisma-specific params should be parseable by psycopg."""
|
||||
url = "postgresql://u:p@h:5432/db?connection_limit=100&pool_timeout=60&sslmode=require"
|
||||
stripped = ProxyExtrasDBManager._strip_prisma_query_params(url)
|
||||
assert "connection_limit" not in stripped
|
||||
assert "pool_timeout" not in stripped
|
||||
assert "sslmode=require" in stripped
|
||||
|
||||
|
||||
def test_strip_prisma_query_params_passthrough_no_query():
|
||||
"""URLs without query strings are returned unchanged."""
|
||||
url = "postgresql://u:p@h:5432/db"
|
||||
assert ProxyExtrasDBManager._strip_prisma_query_params(url) == url
|
||||
|
||||
|
||||
def test_migration_timestamp_extracts_leading_digits():
|
||||
assert _migration_timestamp("20260101000000_add_foo") == 20260101000000
|
||||
assert _migration_timestamp("20250326162113_baseline") == 20250326162113
|
||||
|
||||
|
||||
def test_migration_timestamp_returns_zero_on_malformed():
|
||||
assert _migration_timestamp("0_init") == 0
|
||||
assert _migration_timestamp("not_a_migration") == 0
|
||||
|
||||
|
||||
def test_max_migration_timestamp():
|
||||
names = {"20250326000000_a", "20260415000000_b", "20251115000000_c"}
|
||||
assert _max_migration_timestamp(names) == 20260415000000
|
||||
|
||||
|
||||
def test_max_migration_timestamp_empty_set():
|
||||
assert _max_migration_timestamp(set()) == 0
|
||||
|
||||
|
||||
def test_v1_default_still_calls_resolve_all_migrations(monkeypatch, tmp_path):
|
||||
"""v1 (default) continues to call _resolve_all_migrations on the happy path.
|
||||
|
||||
This is the existing buggy behavior — we're not fixing it in v1, only
|
||||
offering v2 as opt-in. This test pins the default so that a future
|
||||
inadvertent default flip is caught.
|
||||
"""
|
||||
monkeypatch.setattr(ProxyExtrasDBManager, "_get_prisma_dir", lambda: str(tmp_path))
|
||||
(tmp_path / "schema.prisma").write_text("// stub")
|
||||
|
||||
# Stub `prisma migrate deploy` to claim success with pending migrations
|
||||
# applied, which is the code path that triggers the legacy post-migration
|
||||
# sanity check (a call to _resolve_all_migrations).
|
||||
class FakeResult:
|
||||
stdout = "Applied migration.\n"
|
||||
stderr = ""
|
||||
|
||||
def fake_run(cmd, *args, **kwargs):
|
||||
return FakeResult()
|
||||
|
||||
resolve_called = {"n": 0}
|
||||
|
||||
def fake_resolve(*args, **kwargs):
|
||||
resolve_called["n"] += 1
|
||||
|
||||
monkeypatch.setattr("subprocess.run", fake_run)
|
||||
monkeypatch.setattr(ProxyExtrasDBManager, "_resolve_all_migrations", fake_resolve)
|
||||
|
||||
ok = ProxyExtrasDBManager.setup_database(use_migrate=True) # v2 flag NOT set
|
||||
assert ok is True
|
||||
assert resolve_called["n"] == 1, "v1 default should still invoke the legacy path"
|
||||
|
||||
|
||||
def test_v2_db_push_wraps_subprocess_error_as_runtime_error(monkeypatch, tmp_path):
|
||||
"""v2: a failing `prisma db push` must raise RuntimeError, not leak
|
||||
CalledProcessError past proxy_cli.py's `except RuntimeError`."""
|
||||
monkeypatch.setattr(ProxyExtrasDBManager, "_get_prisma_dir", lambda: str(tmp_path))
|
||||
(tmp_path / "schema.prisma").write_text("// stub")
|
||||
|
||||
stderr = "db push error"
|
||||
with patch("subprocess.run", side_effect=_fake_migrate_deploy_failure(1, stderr)):
|
||||
with pytest.raises(RuntimeError, match="prisma db push failed"):
|
||||
ProxyExtrasDBManager.setup_database(use_migrate=False, use_v2_resolver=True)
|
||||
|
||||
|
||||
def test_v2_warn_ahead_of_head_swallows_db_errors(monkeypatch, tmp_path):
|
||||
"""_warn_if_db_ahead_of_head must never raise — it's informational.
|
||||
|
||||
Non-connection DB errors (e.g. InsufficientPrivilege from a user
|
||||
without SELECT on _prisma_migrations) must be caught, not propagated.
|
||||
"""
|
||||
import psycopg
|
||||
|
||||
monkeypatch.setenv("DATABASE_URL", "postgresql://u:p@localhost:9/x")
|
||||
monkeypatch.setattr(ProxyExtrasDBManager, "_get_prisma_dir", lambda: str(tmp_path))
|
||||
(tmp_path / "schema.prisma").write_text("// stub")
|
||||
|
||||
class _FakeConn:
|
||||
def __enter__(self):
|
||||
return self
|
||||
|
||||
def __exit__(self, *a):
|
||||
return False
|
||||
|
||||
def execute(self, *a, **kw):
|
||||
# Simulate an InsufficientPrivilege (subclass of DatabaseError).
|
||||
raise psycopg.errors.InsufficientPrivilege("permission denied")
|
||||
|
||||
def _fake_connect(*a, **kw):
|
||||
return _FakeConn()
|
||||
|
||||
monkeypatch.setattr("psycopg.connect", _fake_connect)
|
||||
|
||||
# Must not raise.
|
||||
ProxyExtrasDBManager._warn_if_db_ahead_of_head(str(tmp_path))
|
||||
|
||||
|
||||
def test_v2_resolve_specific_migration_failure_raises_runtime_error(
|
||||
monkeypatch, tmp_path
|
||||
):
|
||||
"""If marking a migration as applied fails inside P3009 idempotent
|
||||
recovery, the subprocess error must be re-raised as RuntimeError so
|
||||
proxy_cli.py catches it cleanly (instead of leaking CalledProcessError)."""
|
||||
monkeypatch.setattr(
|
||||
ProxyExtrasDBManager, "_warn_if_db_ahead_of_head", lambda _: None
|
||||
)
|
||||
monkeypatch.setattr(ProxyExtrasDBManager, "_get_prisma_dir", lambda: str(tmp_path))
|
||||
(tmp_path / "schema.prisma").write_text("// stub")
|
||||
monkeypatch.setattr(
|
||||
ProxyExtrasDBManager, "_roll_back_migration", lambda *a, **kw: None
|
||||
)
|
||||
|
||||
# First call: migrate deploy -> P3009 idempotent error.
|
||||
# Recovery path tries _resolve_specific_migration; that also raises.
|
||||
def _failing_resolve(*a, **kw):
|
||||
raise subprocess.CalledProcessError(
|
||||
returncode=1,
|
||||
cmd="prisma migrate resolve --applied",
|
||||
stderr="resolve failed",
|
||||
output="",
|
||||
)
|
||||
|
||||
monkeypatch.setattr(
|
||||
ProxyExtrasDBManager, "_resolve_specific_migration", _failing_resolve
|
||||
)
|
||||
|
||||
stderr = (
|
||||
"Error: P3009\nMigration `20260101000000_some_migration` failed\n"
|
||||
"relation already exists"
|
||||
)
|
||||
with patch("subprocess.run", side_effect=_fake_migrate_deploy_failure(1, stderr)):
|
||||
with pytest.raises(
|
||||
RuntimeError, match="Failed to mark migration .* as applied"
|
||||
):
|
||||
ProxyExtrasDBManager.setup_database(use_migrate=True, use_v2_resolver=True)
|
||||
|
||||
|
||||
def test_v2_does_not_call_resolve_all_migrations(monkeypatch, tmp_path):
|
||||
"""v2 must never call _resolve_all_migrations — that's the bug it fixes."""
|
||||
monkeypatch.setattr(
|
||||
ProxyExtrasDBManager, "_warn_if_db_ahead_of_head", lambda _: None
|
||||
)
|
||||
monkeypatch.setattr(ProxyExtrasDBManager, "_get_prisma_dir", lambda: str(tmp_path))
|
||||
(tmp_path / "schema.prisma").write_text("// stub")
|
||||
|
||||
class FakeResult:
|
||||
stdout = "Applied migration.\n"
|
||||
stderr = ""
|
||||
|
||||
monkeypatch.setattr("subprocess.run", lambda *a, **kw: FakeResult())
|
||||
|
||||
resolve_called = {"n": 0}
|
||||
monkeypatch.setattr(
|
||||
ProxyExtrasDBManager,
|
||||
"_resolve_all_migrations",
|
||||
lambda *a, **kw: resolve_called.__setitem__("n", resolve_called["n"] + 1),
|
||||
)
|
||||
|
||||
ok = ProxyExtrasDBManager.setup_database(use_migrate=True, use_v2_resolver=True)
|
||||
assert ok is True
|
||||
assert resolve_called["n"] == 0, "v2 must not invoke the diff-and-force recovery"
|
||||
|
|
@ -148,6 +148,7 @@ _custom_logger_compatible_callbacks_literal = Literal[
|
|||
"vantage",
|
||||
"posthog",
|
||||
"levo",
|
||||
"compression_interception",
|
||||
]
|
||||
cold_storage_custom_logger: Optional[_custom_logger_compatible_callbacks_literal] = None
|
||||
logged_real_time_event_types: Optional[Union[List[str], Literal["*"]]] = None
|
||||
|
|
@ -168,12 +169,12 @@ prometheus_latency_buckets: Optional[List[float]] = None
|
|||
require_auth_for_metrics_endpoint: Optional[bool] = False
|
||||
argilla_batch_size: Optional[int] = None
|
||||
datadog_use_v1: Optional[bool] = False # if you want to use v1 datadog logged payload.
|
||||
gcs_pub_sub_use_v1: Optional[
|
||||
bool
|
||||
] = False # if you want to use v1 gcs pubsub logged payload
|
||||
generic_api_use_v1: Optional[
|
||||
bool
|
||||
] = False # if you want to use v1 generic api logged payload
|
||||
gcs_pub_sub_use_v1: Optional[bool] = (
|
||||
False # if you want to use v1 gcs pubsub logged payload
|
||||
)
|
||||
generic_api_use_v1: Optional[bool] = (
|
||||
False # if you want to use v1 generic api logged payload
|
||||
)
|
||||
argilla_transformation_object: Optional[Dict[str, Any]] = None
|
||||
_async_input_callback: List[
|
||||
Union[str, Callable, "CustomLogger"]
|
||||
|
|
@ -193,26 +194,26 @@ _async_failure_callback: List[
|
|||
pre_call_rules: List[Callable] = []
|
||||
post_call_rules: List[Callable] = []
|
||||
turn_off_message_logging: Optional[bool] = False
|
||||
standard_logging_payload_excluded_fields: Optional[
|
||||
List[str]
|
||||
] = None # Fields to exclude from StandardLoggingPayload before callbacks receive it
|
||||
standard_logging_payload_excluded_fields: Optional[List[str]] = (
|
||||
None # Fields to exclude from StandardLoggingPayload before callbacks receive it
|
||||
)
|
||||
log_raw_request_response: bool = False
|
||||
redact_messages_in_exceptions: Optional[bool] = False
|
||||
redact_user_api_key_info: Optional[bool] = False
|
||||
filter_invalid_headers: Optional[bool] = False
|
||||
add_user_information_to_llm_headers: Optional[
|
||||
bool
|
||||
] = None # adds user_id, team_id, token hash (params from StandardLoggingMetadata) to request headers
|
||||
add_user_information_to_llm_headers: Optional[bool] = (
|
||||
None # adds user_id, team_id, token hash (params from StandardLoggingMetadata) to request headers
|
||||
)
|
||||
store_audit_logs = False # Enterprise feature, allow users to see audit logs
|
||||
skip_system_message_in_guardrail: bool = False
|
||||
### end of callbacks #############
|
||||
|
||||
email: Optional[
|
||||
str
|
||||
] = None # Not used anymore, will be removed in next MAJOR release - https://github.com/BerriAI/litellm/discussions/648
|
||||
token: Optional[
|
||||
str
|
||||
] = None # Not used anymore, will be removed in next MAJOR release - https://github.com/BerriAI/litellm/discussions/648
|
||||
email: Optional[str] = (
|
||||
None # Not used anymore, will be removed in next MAJOR release - https://github.com/BerriAI/litellm/discussions/648
|
||||
)
|
||||
token: Optional[str] = (
|
||||
None # Not used anymore, will be removed in next MAJOR release - https://github.com/BerriAI/litellm/discussions/648
|
||||
)
|
||||
telemetry = True
|
||||
max_tokens: int = DEFAULT_MAX_TOKENS # OpenAI Defaults
|
||||
drop_params = bool(os.getenv("LITELLM_DROP_PARAMS", False))
|
||||
|
|
@ -220,6 +221,9 @@ modify_params = bool(os.getenv("LITELLM_MODIFY_PARAMS", False))
|
|||
use_chat_completions_url_for_anthropic_messages: bool = bool(
|
||||
os.getenv("LITELLM_USE_CHAT_COMPLETIONS_URL_FOR_ANTHROPIC_MESSAGES", False)
|
||||
) # When True, routes OpenAI /v1/messages requests to chat/completions instead of the Responses API
|
||||
route_all_chat_openai_to_responses: bool = (
|
||||
os.getenv("LITELLM_ROUTE_ALL_CHAT_OPENAI_TO_RESPONSES", "false").lower() == "true"
|
||||
) # When True, routes all OpenAI /chat/completions requests through the Responses API bridge
|
||||
retry = True
|
||||
### AUTH ###
|
||||
api_key: Optional[str] = None
|
||||
|
|
@ -274,9 +278,11 @@ use_client: bool = False
|
|||
ssl_verify: Union[str, bool] = True
|
||||
ssl_security_level: Optional[str] = None
|
||||
ssl_certificate: Optional[str] = None
|
||||
ssl_ecdh_curve: Optional[
|
||||
str
|
||||
] = None # Set to 'X25519' to disable PQC and improve performance
|
||||
user_url_validation: bool = True
|
||||
user_url_allowed_hosts: List[str] = []
|
||||
ssl_ecdh_curve: Optional[str] = (
|
||||
None # Set to 'X25519' to disable PQC and improve performance
|
||||
)
|
||||
disable_streaming_logging: bool = False
|
||||
disable_token_counter: bool = False
|
||||
disable_add_transform_inline_image_block: bool = False
|
||||
|
|
@ -330,20 +336,24 @@ enable_loadbalancing_on_batch_endpoints: Optional[bool] = None
|
|||
enable_caching_on_provider_specific_optional_params: bool = (
|
||||
False # feature-flag for caching on optional params - e.g. 'top_k'
|
||||
)
|
||||
caching: bool = False # Not used anymore, will be removed in next MAJOR release - https://github.com/BerriAI/litellm/discussions/648
|
||||
caching_with_models: bool = False # # Not used anymore, will be removed in next MAJOR release - https://github.com/BerriAI/litellm/discussions/648
|
||||
cache: Optional[
|
||||
"Cache"
|
||||
] = None # cache object <- use this - https://docs.litellm.ai/docs/caching
|
||||
caching: bool = (
|
||||
False # Not used anymore, will be removed in next MAJOR release - https://github.com/BerriAI/litellm/discussions/648
|
||||
)
|
||||
caching_with_models: bool = (
|
||||
False # # Not used anymore, will be removed in next MAJOR release - https://github.com/BerriAI/litellm/discussions/648
|
||||
)
|
||||
cache: Optional["Cache"] = (
|
||||
None # cache object <- use this - https://docs.litellm.ai/docs/caching
|
||||
)
|
||||
default_in_memory_ttl: Optional[float] = None
|
||||
default_redis_ttl: Optional[float] = None
|
||||
default_redis_batch_cache_expiry: Optional[float] = None
|
||||
model_alias_map: Dict[str, str] = {}
|
||||
model_group_settings: Optional["ModelGroupSettings"] = None
|
||||
max_budget: float = 0.0 # set the max budget across all providers
|
||||
budget_duration: Optional[
|
||||
str
|
||||
] = None # proxy only - resets budget after fixed duration. You can set duration as seconds ("30s"), minutes ("30m"), hours ("30h"), days ("30d").
|
||||
budget_duration: Optional[str] = (
|
||||
None # proxy only - resets budget after fixed duration. You can set duration as seconds ("30s"), minutes ("30m"), hours ("30h"), days ("30d").
|
||||
)
|
||||
default_soft_budget: float = (
|
||||
DEFAULT_SOFT_BUDGET # by default all litellm proxy keys have a soft budget of 50.0
|
||||
)
|
||||
|
|
@ -352,7 +362,9 @@ forward_traceparent_to_llm_provider: bool = False
|
|||
|
||||
_current_cost = 0.0 # private variable, used if max budget is set
|
||||
error_logs: Dict = {}
|
||||
add_function_to_prompt: bool = False # if function calling not supported by api, append function call details to system prompt
|
||||
add_function_to_prompt: bool = (
|
||||
False # if function calling not supported by api, append function call details to system prompt
|
||||
)
|
||||
client_session: Optional[httpx.Client] = None
|
||||
aclient_session: Optional[httpx.AsyncClient] = None
|
||||
model_fallbacks: Optional[List] = None # Deprecated for 'litellm.fallbacks'
|
||||
|
|
@ -376,6 +388,7 @@ datadog_params: Optional[Union[DatadogInitParams, Dict]] = None
|
|||
aws_sqs_callback_params: Optional[Dict] = None
|
||||
generic_logger_headers: Optional[Dict] = None
|
||||
default_key_generate_params: Optional[Dict] = None
|
||||
default_key_max_budget_alert_emails: Optional[Dict[str, list]] = None
|
||||
upperbound_key_generate_params: Optional[LiteLLM_UpperboundKeyGenerateParams] = None
|
||||
key_generation_settings: Optional["StandardKeyGenerationConfig"] = None
|
||||
default_internal_user_params: Optional[Dict] = None
|
||||
|
|
@ -399,7 +412,9 @@ prometheus_emit_stream_label: bool = False
|
|||
disable_add_prefix_to_prompt: bool = (
|
||||
False # used by anthropic, to disable adding prefix to prompt
|
||||
)
|
||||
disable_copilot_system_to_assistant: bool = False # If false (default), converts all 'system' role messages to 'assistant' for GitHub Copilot compatibility. Set to true to disable this behavior.
|
||||
disable_copilot_system_to_assistant: bool = (
|
||||
False # If false (default), converts all 'system' role messages to 'assistant' for GitHub Copilot compatibility. Set to true to disable this behavior.
|
||||
)
|
||||
public_mcp_servers: Optional[List[str]] = None
|
||||
public_model_groups: Optional[List[str]] = None
|
||||
public_agent_groups: Optional[List[str]] = None
|
||||
|
|
@ -408,9 +423,9 @@ public_agent_groups: Optional[List[str]] = None
|
|||
# Old format: { "displayName": "url" } (for backward compatibility)
|
||||
public_model_groups_links: Dict[str, Union[str, Dict[str, Any]]] = {}
|
||||
#### REQUEST PRIORITIZATION #######
|
||||
priority_reservation: Optional[
|
||||
Dict[str, Union[float, "PriorityReservationDict"]]
|
||||
] = None
|
||||
priority_reservation: Optional[Dict[str, Union[float, "PriorityReservationDict"]]] = (
|
||||
None
|
||||
)
|
||||
# priority_reservation_settings is lazy-loaded via __getattr__
|
||||
# Only declare for type checking - at runtime __getattr__ handles it
|
||||
if TYPE_CHECKING:
|
||||
|
|
@ -418,13 +433,17 @@ if TYPE_CHECKING:
|
|||
|
||||
|
||||
######## Networking Settings ########
|
||||
use_aiohttp_transport: bool = True # Older variable, aiohttp is now the default. use disable_aiohttp_transport instead.
|
||||
use_aiohttp_transport: bool = (
|
||||
True # Older variable, aiohttp is now the default. use disable_aiohttp_transport instead.
|
||||
)
|
||||
aiohttp_trust_env: bool = False # set to true to use HTTP_ Proxy settings
|
||||
disable_aiohttp_transport: bool = False # Set this to true to use httpx instead
|
||||
disable_aiohttp_trust_env: bool = (
|
||||
False # When False, aiohttp will respect HTTP(S)_PROXY env vars
|
||||
)
|
||||
force_ipv4: bool = False # when True, litellm will force ipv4 for all LLM requests. Some users have seen httpx ConnectionError when using ipv6.
|
||||
force_ipv4: bool = (
|
||||
False # when True, litellm will force ipv4 for all LLM requests. Some users have seen httpx ConnectionError when using ipv6.
|
||||
)
|
||||
network_mock: bool = False # When True, use mock transport — no real network calls
|
||||
|
||||
####### STOP SEQUENCE LIMIT #######
|
||||
|
|
@ -439,13 +458,13 @@ context_window_fallbacks: Optional[List] = None
|
|||
content_policy_fallbacks: Optional[List] = None
|
||||
allowed_fails: int = 3
|
||||
allow_dynamic_callback_disabling: bool = True
|
||||
num_retries_per_request: Optional[
|
||||
int
|
||||
] = None # for the request overall (incl. fallbacks + model retries)
|
||||
num_retries_per_request: Optional[int] = (
|
||||
None # for the request overall (incl. fallbacks + model retries)
|
||||
)
|
||||
####### SECRET MANAGERS #####################
|
||||
secret_manager_client: Optional[
|
||||
Any
|
||||
] = None # list of instantiated key management clients - e.g. azure kv, infisical, etc.
|
||||
secret_manager_client: Optional[Any] = (
|
||||
None # list of instantiated key management clients - e.g. azure kv, infisical, etc.
|
||||
)
|
||||
_google_kms_resource_name: Optional[str] = None
|
||||
_key_management_system: Optional["KeyManagementSystem"] = None
|
||||
# Note: KeyManagementSettings must be eagerly imported because _key_management_settings
|
||||
|
|
@ -458,12 +477,12 @@ output_parse_pii: bool = False
|
|||
from litellm.litellm_core_utils.get_model_cost_map import get_model_cost_map
|
||||
|
||||
model_cost = get_model_cost_map(url=model_cost_map_url)
|
||||
cost_discount_config: Dict[
|
||||
str, float
|
||||
] = {} # Provider-specific cost discounts {"vertex_ai": 0.05} = 5% discount
|
||||
cost_margin_config: Dict[
|
||||
str, Union[float, Dict[str, float]]
|
||||
] = {} # Provider-specific or global cost margins. Examples:
|
||||
cost_discount_config: Dict[str, float] = (
|
||||
{}
|
||||
) # Provider-specific cost discounts {"vertex_ai": 0.05} = 5% discount
|
||||
cost_margin_config: Dict[str, Union[float, Dict[str, float]]] = (
|
||||
{}
|
||||
) # Provider-specific or global cost margins. Examples:
|
||||
# Percentage: {"openai": 0.10} = 10% margin
|
||||
# Fixed: {"openai": {"fixed_amount": 0.001}} = $0.001 per request
|
||||
# Global: {"global": 0.05} = 5% global margin on all providers
|
||||
|
|
@ -1313,12 +1332,12 @@ from . import rag
|
|||
from .types.llms.custom_llm import CustomLLMItem
|
||||
|
||||
custom_provider_map: List[CustomLLMItem] = []
|
||||
_custom_providers: List[
|
||||
str
|
||||
] = [] # internal helper util, used to track names of custom providers
|
||||
disable_hf_tokenizer_download: Optional[
|
||||
bool
|
||||
] = None # disable huggingface tokenizer download. Defaults to openai clk100
|
||||
_custom_providers: List[str] = (
|
||||
[]
|
||||
) # internal helper util, used to track names of custom providers
|
||||
disable_hf_tokenizer_download: Optional[bool] = (
|
||||
None # disable huggingface tokenizer download. Defaults to openai clk100
|
||||
)
|
||||
global_disable_no_log_param: bool = False
|
||||
|
||||
### CLI UTILITIES ###
|
||||
|
|
@ -1486,6 +1505,9 @@ if TYPE_CHECKING:
|
|||
from .llms.bedrock.messages.invoke_transformations.anthropic_claude3_transformation import (
|
||||
AmazonAnthropicClaudeMessagesConfig as AmazonAnthropicClaudeMessagesConfig,
|
||||
)
|
||||
from .llms.bedrock.messages.mantle_transformation import (
|
||||
AmazonMantleMessagesConfig as AmazonMantleMessagesConfig,
|
||||
)
|
||||
from .llms.together_ai.chat import TogetherAIConfig as TogetherAIConfig
|
||||
from .llms.nlp_cloud.chat.handler import NLPCloudConfig as NLPCloudConfig
|
||||
from .llms.vertex_ai.gemini.vertex_and_google_ai_studio_gemini import (
|
||||
|
|
|
|||
|
|
@ -14,6 +14,7 @@ How it works:
|
|||
This makes importing litellm much faster because we don't load heavy dependencies
|
||||
until they're actually needed.
|
||||
"""
|
||||
|
||||
import importlib
|
||||
import sys
|
||||
from typing import Any, Optional, cast, Callable
|
||||
|
|
|
|||
|
|
@ -171,6 +171,7 @@ LLM_CONFIG_NAMES = (
|
|||
"CohereChatConfig",
|
||||
"AnthropicMessagesConfig",
|
||||
"AmazonAnthropicClaudeMessagesConfig",
|
||||
"AmazonMantleMessagesConfig",
|
||||
"TogetherAIConfig",
|
||||
"NLPCloudConfig",
|
||||
"VertexGeminiConfig",
|
||||
|
|
@ -715,6 +716,10 @@ _LLM_CONFIGS_IMPORT_MAP = {
|
|||
".llms.bedrock.messages.invoke_transformations.anthropic_claude3_transformation",
|
||||
"AmazonAnthropicClaudeMessagesConfig",
|
||||
),
|
||||
"AmazonMantleMessagesConfig": (
|
||||
".llms.bedrock.messages.mantle_transformation",
|
||||
"AmazonMantleMessagesConfig",
|
||||
),
|
||||
"TogetherAIConfig": (".llms.together_ai.chat", "TogetherAIConfig"),
|
||||
"NLPCloudConfig": (".llms.nlp_cloud.chat.handler", "NLPCloudConfig"),
|
||||
"VertexGeminiConfig": (
|
||||
|
|
|
|||
|
|
@ -120,9 +120,9 @@ def _get_a2a_model_info(a2a_client: Any, kwargs: Dict[str, Any]) -> str:
|
|||
litellm_logging_obj.model = model
|
||||
litellm_logging_obj.custom_llm_provider = custom_llm_provider
|
||||
litellm_logging_obj.model_call_details["model"] = model
|
||||
litellm_logging_obj.model_call_details[
|
||||
"custom_llm_provider"
|
||||
] = custom_llm_provider
|
||||
litellm_logging_obj.model_call_details["custom_llm_provider"] = (
|
||||
custom_llm_provider
|
||||
)
|
||||
|
||||
return agent_name
|
||||
|
||||
|
|
|
|||
|
|
@ -99,9 +99,7 @@ class BedrockAgentCoreA2AHandler:
|
|||
)
|
||||
)
|
||||
|
||||
verbose_logger.info(
|
||||
f"BedrockAgentCore A2A: Sending streaming request to {url}"
|
||||
)
|
||||
verbose_logger.info(f"BedrockAgentCore A2A: Sending streaming request to {url}")
|
||||
|
||||
client = get_async_httpx_client(
|
||||
llm_provider=cast(Any, httpxSpecialProvider.A2AProvider),
|
||||
|
|
|
|||
|
|
@ -168,9 +168,9 @@ class A2AStreamingIterator:
|
|||
result: Dict[str, Any] = {
|
||||
"id": getattr(self.request, "id", "unknown"),
|
||||
"jsonrpc": "2.0",
|
||||
"usage": usage.model_dump()
|
||||
if hasattr(usage, "model_dump")
|
||||
else dict(usage),
|
||||
"usage": (
|
||||
usage.model_dump() if hasattr(usage, "model_dump") else dict(usage)
|
||||
),
|
||||
}
|
||||
|
||||
# Add final chunk result if available
|
||||
|
|
|
|||
|
|
@ -1,6 +1,7 @@
|
|||
"""
|
||||
Anthropic module for LiteLLM
|
||||
"""
|
||||
|
||||
from .messages import acreate, create
|
||||
|
||||
__all__ = ["acreate", "create"]
|
||||
|
|
|
|||
|
|
@ -38,7 +38,7 @@ async def acreate(
|
|||
top_k: Optional[int] = None,
|
||||
top_p: Optional[float] = None,
|
||||
container: Optional[Dict] = None,
|
||||
**kwargs
|
||||
**kwargs,
|
||||
) -> Union[AnthropicMessagesResponse, AsyncIterator]:
|
||||
"""
|
||||
Async wrapper for Anthropic's messages API
|
||||
|
|
@ -97,7 +97,7 @@ def create(
|
|||
top_k: Optional[int] = None,
|
||||
top_p: Optional[float] = None,
|
||||
container: Optional[Dict] = None,
|
||||
**kwargs
|
||||
**kwargs,
|
||||
) -> Union[
|
||||
AnthropicMessagesResponse,
|
||||
AsyncIterator[Any],
|
||||
|
|
|
|||
|
|
@ -78,7 +78,9 @@ class CachingHandlerResponse(BaseModel):
|
|||
|
||||
cached_result: Optional[Any] = None
|
||||
final_embedding_cached_response: Optional[EmbeddingResponse] = None
|
||||
embedding_all_elements_cache_hit: bool = False # this is set to True when all elements in the list have a cache hit in the embedding cache, if true return the final_embedding_cached_response no need to make an API call
|
||||
embedding_all_elements_cache_hit: bool = (
|
||||
False # this is set to True when all elements in the list have a cache hit in the embedding cache, if true return the final_embedding_cached_response no need to make an API call
|
||||
)
|
||||
|
||||
|
||||
in_memory_cache_obj = InMemoryCache()
|
||||
|
|
@ -1014,9 +1016,9 @@ class LLMCachingHandler:
|
|||
}
|
||||
|
||||
if litellm.cache is not None:
|
||||
litellm_params[
|
||||
"preset_cache_key"
|
||||
] = litellm.cache._get_preset_cache_key_from_kwargs(**kwargs)
|
||||
litellm_params["preset_cache_key"] = (
|
||||
litellm.cache._get_preset_cache_key_from_kwargs(**kwargs)
|
||||
)
|
||||
else:
|
||||
litellm_params["preset_cache_key"] = None
|
||||
|
||||
|
|
|
|||
|
|
@ -1,6 +1,7 @@
|
|||
"""GCS Cache implementation
|
||||
Supports syncing responses to Google Cloud Storage Buckets using HTTP requests.
|
||||
"""
|
||||
|
||||
import json
|
||||
import asyncio
|
||||
from typing import Optional
|
||||
|
|
|
|||
|
|
@ -142,9 +142,7 @@ class ResponsesToCompletionBridgeHandler:
|
|||
custom_llm_provider=custom_llm_provider,
|
||||
)
|
||||
|
||||
def completion(
|
||||
self, *args, **kwargs
|
||||
) -> Union[
|
||||
def completion(self, *args, **kwargs) -> Union[
|
||||
Coroutine[Any, Any, Union["ModelResponse", "CustomStreamWrapper"]],
|
||||
"ModelResponse",
|
||||
"CustomStreamWrapper",
|
||||
|
|
|
|||
|
|
@ -300,10 +300,10 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
if key in ("max_tokens", "max_completion_tokens"):
|
||||
responses_api_request["max_output_tokens"] = value
|
||||
elif key == "tools" and value is not None:
|
||||
responses_api_request[
|
||||
"tools"
|
||||
] = self._convert_tools_to_responses_format(
|
||||
cast(List[Dict[str, Any]], value)
|
||||
responses_api_request["tools"] = (
|
||||
self._convert_tools_to_responses_format(
|
||||
cast(List[Dict[str, Any]], value)
|
||||
)
|
||||
)
|
||||
elif key == "response_format":
|
||||
text_format = self._transform_response_format_to_text_format(value)
|
||||
|
|
@ -506,9 +506,11 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
annotations=annotations,
|
||||
reasoning_items=cast(
|
||||
Optional[List[ChatCompletionReasoningItem]],
|
||||
[pending_reasoning_item]
|
||||
if pending_reasoning_item is not None
|
||||
else None,
|
||||
(
|
||||
[pending_reasoning_item]
|
||||
if pending_reasoning_item is not None
|
||||
else None
|
||||
),
|
||||
),
|
||||
)
|
||||
|
||||
|
|
@ -566,9 +568,11 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
reasoning_content=reasoning_content,
|
||||
reasoning_items=cast(
|
||||
Optional[List[ChatCompletionReasoningItem]],
|
||||
[pending_reasoning_item]
|
||||
if pending_reasoning_item is not None
|
||||
else None,
|
||||
(
|
||||
[pending_reasoning_item]
|
||||
if pending_reasoning_item is not None
|
||||
else None
|
||||
),
|
||||
),
|
||||
)
|
||||
choices.append(
|
||||
|
|
@ -1154,9 +1158,9 @@ class OpenAiResponsesToChatCompletionStreamIterator(BaseModelResponseIterator):
|
|||
)
|
||||
|
||||
if provider_specific_fields:
|
||||
function_chunk[
|
||||
"provider_specific_fields"
|
||||
] = provider_specific_fields
|
||||
function_chunk["provider_specific_fields"] = (
|
||||
provider_specific_fields
|
||||
)
|
||||
|
||||
tool_call_index = parsed_chunk.get("output_index", 0)
|
||||
tool_call_chunk = ChatCompletionToolCallChunk(
|
||||
|
|
@ -1229,9 +1233,9 @@ class OpenAiResponsesToChatCompletionStreamIterator(BaseModelResponseIterator):
|
|||
|
||||
# Add provider_specific_fields to function if present
|
||||
if provider_specific_fields:
|
||||
function_chunk[
|
||||
"provider_specific_fields"
|
||||
] = provider_specific_fields
|
||||
function_chunk["provider_specific_fields"] = (
|
||||
provider_specific_fields
|
||||
)
|
||||
|
||||
tool_call_index = parsed_chunk.get("output_index", 0)
|
||||
tool_call_chunk = ChatCompletionToolCallChunk(
|
||||
|
|
|
|||
|
|
@ -1,9 +1,9 @@
|
|||
"""
|
||||
Main compress() function — orchestrates BM25/embedding scoring, message stubbing,
|
||||
and retrieval tool injection.
|
||||
Main compress() function — normalizes input messages, orchestrates BM25/embedding
|
||||
scoring, message stubbing, and retrieval tool injection.
|
||||
"""
|
||||
|
||||
from typing import Any, Dict, List, Optional, Set, Union, cast
|
||||
from typing import Any, Dict, List, Optional, Set, Tuple, Union, cast
|
||||
|
||||
from litellm.caching.dual_cache import DualCache
|
||||
from litellm.compression.message_stubbing import (
|
||||
|
|
@ -15,27 +15,196 @@ from litellm.compression.retrieval_tool import build_retrieval_tool
|
|||
from litellm.compression.scoring.bm25 import bm25_score_messages
|
||||
from litellm.litellm_core_utils.token_counter import token_counter
|
||||
from litellm.types.compression import CompressedResult
|
||||
from litellm.types.utils import AllMessageValues, Message
|
||||
from litellm.types.utils import CallTypes
|
||||
|
||||
# CallTypes that produce Anthropic-shaped messages (structured content blocks).
|
||||
# Everything else is treated as OpenAI chat-completions shape.
|
||||
_ANTHROPIC_CALL_TYPES = frozenset({CallTypes.anthropic_messages.value})
|
||||
# CallTypes that are valid targets for compression. Compression operates on
|
||||
# message-shaped inputs, so we only accept call types whose payload is a list
|
||||
# of role/content messages.
|
||||
_SUPPORTED_CALL_TYPES = frozenset(
|
||||
{
|
||||
CallTypes.completion.value,
|
||||
CallTypes.acompletion.value,
|
||||
CallTypes.anthropic_messages.value,
|
||||
}
|
||||
)
|
||||
|
||||
|
||||
def _normalize_call_type(call_type: Union[CallTypes, str]) -> str:
|
||||
"""Return the string value for a ``CallTypes`` enum or a raw string."""
|
||||
if isinstance(call_type, CallTypes):
|
||||
return call_type.value
|
||||
return call_type
|
||||
|
||||
|
||||
def _is_anthropic_call_type(call_type: str) -> bool:
|
||||
return call_type in _ANTHROPIC_CALL_TYPES
|
||||
|
||||
|
||||
def _build_retrieval_tools(keys: List[str], call_type: str) -> List[dict]:
|
||||
"""
|
||||
Build retrieval tool definitions in the target request schema.
|
||||
|
||||
- Chat-completions call types: keep OpenAI function-tool schema.
|
||||
- Anthropic messages call type: remap to Anthropic's custom tool schema.
|
||||
"""
|
||||
if not keys:
|
||||
return []
|
||||
|
||||
openai_tools = [build_retrieval_tool(keys)]
|
||||
if not _is_anthropic_call_type(call_type):
|
||||
return openai_tools
|
||||
|
||||
# Lazy import to avoid introducing provider transformation imports during
|
||||
# module import for non-Anthropic call paths.
|
||||
from litellm.llms.anthropic.chat.transformation import AnthropicConfig
|
||||
|
||||
anthropic_tools, _mcp_servers = AnthropicConfig()._map_tools(openai_tools)
|
||||
return cast(List[dict], anthropic_tools)
|
||||
|
||||
|
||||
def _content_to_text(content: Any) -> str:
|
||||
"""
|
||||
Convert OpenAI/Anthropic message content blocks to plain text.
|
||||
|
||||
Text extraction policy:
|
||||
- Include text-bearing fields only (`text` blocks + string values).
|
||||
- For `tool_result`, expand into nested `content` items.
|
||||
- Ignore non-textual blocks (images/documents/tool metadata/thinking metadata).
|
||||
|
||||
Implemented iteratively (stack-based) to avoid unbounded recursion.
|
||||
"""
|
||||
parts: List[str] = []
|
||||
stack: List[Any] = [content]
|
||||
while stack:
|
||||
item = stack.pop()
|
||||
if isinstance(item, str):
|
||||
parts.append(item)
|
||||
elif isinstance(item, list):
|
||||
# Push list items in reverse order so they are processed left-to-right.
|
||||
for element in reversed(item):
|
||||
stack.append(element)
|
||||
elif isinstance(item, dict):
|
||||
item_type = item.get("type")
|
||||
if item_type == "text":
|
||||
parts.append(str(item.get("text", "")))
|
||||
elif item_type == "tool_result":
|
||||
stack.append(item.get("content", ""))
|
||||
return " ".join(parts)
|
||||
|
||||
|
||||
def _normalize_messages_for_compression(
|
||||
messages: List[dict],
|
||||
call_type: str,
|
||||
) -> Tuple[List[dict], List[dict]]:
|
||||
"""
|
||||
Normalize each original message to a text-surrogate content for scoring.
|
||||
|
||||
Returns:
|
||||
(normalized_messages, original_messages_copy)
|
||||
"""
|
||||
if call_type not in _SUPPORTED_CALL_TYPES:
|
||||
raise ValueError(
|
||||
f"Unsupported call_type={call_type!r} for compression. "
|
||||
f"Expected one of: {sorted(_SUPPORTED_CALL_TYPES)}."
|
||||
)
|
||||
|
||||
original_messages: List[Dict[str, Any]] = [dict(m) for m in messages]
|
||||
|
||||
normalized_messages: List[dict] = []
|
||||
for msg in original_messages:
|
||||
normalized_messages.append(
|
||||
{
|
||||
**msg,
|
||||
"content": _content_to_text(msg.get("content", "")),
|
||||
}
|
||||
)
|
||||
return normalized_messages, original_messages
|
||||
|
||||
|
||||
def _extract_last_user_message(messages: List[dict]) -> str:
|
||||
"""Return the text content of the last user message."""
|
||||
for msg in reversed(messages):
|
||||
if msg.get("role") == "user":
|
||||
content = msg.get("content", "")
|
||||
if isinstance(content, str):
|
||||
return content
|
||||
if isinstance(content, list):
|
||||
parts = []
|
||||
for part in content:
|
||||
if isinstance(part, dict) and part.get("type") == "text":
|
||||
parts.append(part.get("text", ""))
|
||||
elif isinstance(part, str):
|
||||
parts.append(part)
|
||||
return " ".join(parts)
|
||||
return _content_to_text(msg.get("content", ""))
|
||||
return ""
|
||||
|
||||
|
||||
def _extract_tool_use_ids(content: Any) -> List[str]:
|
||||
if not isinstance(content, list):
|
||||
return []
|
||||
tool_use_ids: List[str] = []
|
||||
for part in content:
|
||||
if not isinstance(part, dict):
|
||||
continue
|
||||
if part.get("type") != "tool_use":
|
||||
continue
|
||||
tool_use_id = part.get("id")
|
||||
if isinstance(tool_use_id, str) and tool_use_id:
|
||||
tool_use_ids.append(tool_use_id)
|
||||
return tool_use_ids
|
||||
|
||||
|
||||
def _extract_tool_result_ids(content: Any) -> Set[str]:
|
||||
if not isinstance(content, list):
|
||||
return set()
|
||||
tool_result_ids: Set[str] = set()
|
||||
for part in content:
|
||||
if not isinstance(part, dict):
|
||||
continue
|
||||
if part.get("type") != "tool_result":
|
||||
continue
|
||||
tool_use_id = part.get("tool_use_id")
|
||||
if isinstance(tool_use_id, str) and tool_use_id:
|
||||
tool_result_ids.add(tool_use_id)
|
||||
return tool_result_ids
|
||||
|
||||
|
||||
def _extract_anthropic_tool_exchange_spans(
|
||||
messages: List[dict],
|
||||
) -> Tuple[List[Set[int]], Optional[str]]:
|
||||
"""
|
||||
Return atomic 2-message spans for Anthropic tool exchanges.
|
||||
|
||||
Each assistant message containing `tool_use` must be immediately followed by a
|
||||
user message containing matching `tool_result` blocks for all tool_use ids.
|
||||
"""
|
||||
spans: List[Set[int]] = []
|
||||
i = 0
|
||||
while i < len(messages):
|
||||
current = messages[i]
|
||||
if current.get("role") != "assistant":
|
||||
i += 1
|
||||
continue
|
||||
|
||||
tool_use_ids = _extract_tool_use_ids(current.get("content"))
|
||||
if not tool_use_ids:
|
||||
i += 1
|
||||
continue
|
||||
|
||||
if i + 1 >= len(messages):
|
||||
return [], "invalid_anthropic_tool_sequence"
|
||||
|
||||
next_msg = messages[i + 1]
|
||||
if next_msg.get("role") != "user":
|
||||
return [], "invalid_anthropic_tool_sequence"
|
||||
|
||||
tool_result_ids = _extract_tool_result_ids(next_msg.get("content"))
|
||||
if not tool_result_ids:
|
||||
return [], "invalid_anthropic_tool_sequence"
|
||||
|
||||
for tool_use_id in tool_use_ids:
|
||||
if tool_use_id not in tool_result_ids:
|
||||
return [], "invalid_anthropic_tool_sequence"
|
||||
|
||||
spans.append({i, i + 1})
|
||||
i += 2
|
||||
|
||||
return spans, None
|
||||
|
||||
|
||||
def _get_protected_indices(messages: List[dict]) -> List[int]:
|
||||
"""
|
||||
Return indices of messages that must never be compressed:
|
||||
|
|
@ -87,9 +256,98 @@ def _combine_scores(
|
|||
return [bm25_weight * b + emb_weight * e for b, e in zip(norm_bm25, norm_emb)]
|
||||
|
||||
|
||||
def _select_kept_indices_for_budget(
|
||||
normalized_messages: List[dict],
|
||||
original_messages: List[dict],
|
||||
combined_scores: List[float],
|
||||
compression_target: int,
|
||||
model: str,
|
||||
initial_kept_indices: Set[int],
|
||||
tool_exchange_spans: List[Set[int]],
|
||||
) -> Tuple[Set[int], Dict[int, dict]]:
|
||||
kept_indices = set(initial_kept_indices)
|
||||
current_tokens = 0
|
||||
for i in kept_indices:
|
||||
current_tokens += token_counter(
|
||||
model=model,
|
||||
text=cast(str, normalized_messages[i].get("content", "") or ""),
|
||||
)
|
||||
|
||||
# Fill token budget from highest-scoring units.
|
||||
# A unit is either:
|
||||
# 1) a single message index, or
|
||||
# 2) an Anthropic tool-exchange span that must be kept/dropped atomically.
|
||||
truncated_overrides: Dict[int, dict] = {} # idx -> truncated message dict
|
||||
span_id_by_index: Dict[int, int] = {}
|
||||
for span_id, span in enumerate(tool_exchange_spans):
|
||||
for idx in span:
|
||||
span_id_by_index[idx] = span_id
|
||||
|
||||
# Build single-message candidate units (non-span messages).
|
||||
candidate_units: List[Tuple[float, Tuple[int, ...], bool]] = []
|
||||
for idx in range(len(normalized_messages)):
|
||||
if idx in span_id_by_index or idx in kept_indices:
|
||||
continue
|
||||
candidate_units.append((combined_scores[idx], (idx,), True))
|
||||
|
||||
# Build span candidate units (atomic keep/drop for tool exchanges).
|
||||
for span in tool_exchange_spans:
|
||||
span_indices = tuple(sorted(span))
|
||||
if any(idx in kept_indices for idx in span_indices):
|
||||
continue
|
||||
span_score = max(combined_scores[idx] for idx in span_indices)
|
||||
candidate_units.append((span_score, span_indices, False))
|
||||
|
||||
# Sort by descending relevance score.
|
||||
candidate_units.sort(key=lambda item: item[0], reverse=True)
|
||||
|
||||
for _score, indices, can_truncate in candidate_units:
|
||||
if any(idx in kept_indices for idx in indices):
|
||||
continue
|
||||
msg_tokens = 0
|
||||
for idx in indices:
|
||||
msg_tokens += token_counter(
|
||||
model=model,
|
||||
text=cast(str, normalized_messages[idx].get("content", "") or ""),
|
||||
)
|
||||
remaining = compression_target - current_tokens
|
||||
|
||||
if remaining <= 0:
|
||||
break # budget exhausted
|
||||
|
||||
if current_tokens + msg_tokens <= compression_target:
|
||||
# Fits entirely
|
||||
kept_indices.update(indices)
|
||||
current_tokens += msg_tokens
|
||||
elif can_truncate and len(indices) == 1 and remaining >= 100:
|
||||
# Too large to fit whole single message, but we have budget — truncate it.
|
||||
idx = indices[0]
|
||||
truncated = truncate_message(original_messages[idx], remaining)
|
||||
truncated_tokens = token_counter(
|
||||
model=model,
|
||||
text=truncated.get("content", "") or "",
|
||||
)
|
||||
truncated_overrides[idx] = truncated
|
||||
kept_indices.add(idx)
|
||||
current_tokens += truncated_tokens
|
||||
|
||||
return kept_indices, truncated_overrides
|
||||
|
||||
|
||||
def _get_dropped_tool_span_indices(
|
||||
kept_indices: Set[int], tool_exchange_spans: List[Set[int]]
|
||||
) -> Set[int]:
|
||||
dropped_tool_span_indices: Set[int] = set()
|
||||
for span in tool_exchange_spans:
|
||||
if not any(idx in kept_indices for idx in span):
|
||||
dropped_tool_span_indices.update(span)
|
||||
return dropped_tool_span_indices
|
||||
|
||||
|
||||
def compress(
|
||||
messages: List[dict],
|
||||
model: str,
|
||||
call_type: Union[CallTypes, str] = CallTypes.completion,
|
||||
compression_trigger: int = 200_000,
|
||||
compression_target: Optional[int] = None,
|
||||
embedding_model: Optional[str] = None,
|
||||
|
|
@ -108,6 +366,12 @@ def compress(
|
|||
Parameters:
|
||||
messages: The conversation messages to (potentially) compress.
|
||||
model: The LLM model name — used for token counting.
|
||||
call_type: The LiteLLM call type whose message schema these messages
|
||||
follow. Supported values:
|
||||
- ``CallTypes.completion`` / ``CallTypes.acompletion`` — OpenAI
|
||||
chat-completions shape (default)
|
||||
- ``CallTypes.anthropic_messages`` — Anthropic Messages shape
|
||||
(structured content blocks + atomic tool exchanges)
|
||||
compression_trigger: Only compress if input exceeds this token count.
|
||||
compression_target: Target token count after compression.
|
||||
Defaults to ``compression_trigger // 2``.
|
||||
|
|
@ -122,29 +386,37 @@ def compress(
|
|||
A ``CompressedResult`` dict containing compressed messages, token
|
||||
counts, a cache of original content, and the retrieval tool definition.
|
||||
"""
|
||||
call_type_str = _normalize_call_type(call_type)
|
||||
normalized_messages, original_messages = _normalize_messages_for_compression(
|
||||
messages=messages,
|
||||
call_type=call_type_str,
|
||||
)
|
||||
|
||||
if compression_target is None:
|
||||
compression_target = compression_trigger * 7 // 10
|
||||
|
||||
original_tokens = token_counter(
|
||||
model=model, messages=cast(List[Union[AllMessageValues, Message]], messages)
|
||||
model=model,
|
||||
messages=cast(List[Any], original_messages),
|
||||
)
|
||||
|
||||
# Pass through if below trigger
|
||||
if original_tokens <= compression_trigger:
|
||||
return CompressedResult(
|
||||
messages=messages,
|
||||
messages=original_messages,
|
||||
original_tokens=original_tokens,
|
||||
compressed_tokens=original_tokens,
|
||||
compression_ratio=0.0,
|
||||
cache={},
|
||||
tools=[],
|
||||
compression_skipped_reason="below_trigger",
|
||||
)
|
||||
|
||||
# Extract query for relevance scoring
|
||||
query = _extract_last_user_message(messages)
|
||||
query = _extract_last_user_message(normalized_messages)
|
||||
|
||||
# Score each message
|
||||
bm25_scores = bm25_score_messages(query, messages)
|
||||
bm25_scores = bm25_score_messages(query, normalized_messages)
|
||||
|
||||
if embedding_model:
|
||||
from litellm.compression.scoring.embedding_scorer import (
|
||||
|
|
@ -153,7 +425,7 @@ def compress(
|
|||
|
||||
emb_scores = embedding_score_messages(
|
||||
query,
|
||||
messages,
|
||||
normalized_messages,
|
||||
model=embedding_model,
|
||||
cache=compression_cache,
|
||||
embedding_model_params=embedding_model_params,
|
||||
|
|
@ -162,94 +434,80 @@ def compress(
|
|||
else:
|
||||
combined_scores = bm25_scores
|
||||
|
||||
# Sort message indices by score descending
|
||||
ranked_indices = sorted(
|
||||
range(len(messages)),
|
||||
key=lambda i: combined_scores[i],
|
||||
reverse=True,
|
||||
)
|
||||
|
||||
# Protected messages are never compressed
|
||||
protected_indices = _get_protected_indices(messages)
|
||||
protected_indices = _get_protected_indices(normalized_messages)
|
||||
kept_indices: Set[int] = set(protected_indices)
|
||||
|
||||
# Count tokens for protected messages
|
||||
current_tokens = 0
|
||||
for i in kept_indices:
|
||||
current_tokens += token_counter(
|
||||
model=model, text=messages[i].get("content", "") or ""
|
||||
tool_exchange_spans: List[Set[int]] = []
|
||||
if _is_anthropic_call_type(call_type_str):
|
||||
tool_exchange_spans, tool_sequence_error = (
|
||||
_extract_anthropic_tool_exchange_spans(original_messages)
|
||||
)
|
||||
|
||||
# Fill token budget from highest-scoring messages.
|
||||
# For each candidate (ranked by relevance):
|
||||
# - If it fits entirely → keep it as-is.
|
||||
# - If it doesn't fit but there's meaningful remaining budget → truncate it
|
||||
# to fill as much of the budget as possible.
|
||||
# - Otherwise → stub it (pointer only, content goes to cache).
|
||||
# Multiple messages may be truncated so we preserve partial content from
|
||||
# several high-scoring messages rather than fully stubbing all but one.
|
||||
truncated_overrides: Dict[int, dict] = {} # idx -> truncated message dict
|
||||
|
||||
for idx in ranked_indices:
|
||||
if idx in kept_indices:
|
||||
continue
|
||||
msg_content = messages[idx].get("content", "") or ""
|
||||
msg_tokens = token_counter(model=model, text=msg_content)
|
||||
remaining = compression_target - current_tokens
|
||||
|
||||
if remaining <= 0:
|
||||
break # budget exhausted
|
||||
|
||||
if current_tokens + msg_tokens <= compression_target:
|
||||
# Fits entirely
|
||||
kept_indices.add(idx)
|
||||
current_tokens += msg_tokens
|
||||
elif remaining >= 100:
|
||||
# Too large to fit whole, but we have budget — truncate it.
|
||||
truncated = truncate_message(messages[idx], remaining)
|
||||
truncated_tokens = token_counter(
|
||||
model=model,
|
||||
text=truncated.get("content", "") or "",
|
||||
if tool_sequence_error is not None:
|
||||
return CompressedResult(
|
||||
messages=original_messages,
|
||||
original_tokens=original_tokens,
|
||||
compressed_tokens=original_tokens,
|
||||
compression_ratio=0.0,
|
||||
cache={},
|
||||
tools=[],
|
||||
compression_skipped_reason=tool_sequence_error,
|
||||
)
|
||||
truncated_overrides[idx] = truncated
|
||||
kept_indices.add(idx)
|
||||
current_tokens += truncated_tokens
|
||||
|
||||
for span in tool_exchange_spans:
|
||||
# If any message in the span is protected, keep the whole span.
|
||||
if any(idx in kept_indices for idx in span):
|
||||
kept_indices.update(span)
|
||||
|
||||
kept_indices, truncated_overrides = _select_kept_indices_for_budget(
|
||||
normalized_messages=normalized_messages,
|
||||
original_messages=original_messages,
|
||||
combined_scores=combined_scores,
|
||||
compression_target=compression_target,
|
||||
model=model,
|
||||
initial_kept_indices=kept_indices,
|
||||
tool_exchange_spans=tool_exchange_spans,
|
||||
)
|
||||
|
||||
# Build compressed messages and cache
|
||||
compressed_messages: List[dict] = []
|
||||
cache: Dict[str, str] = {}
|
||||
used_keys: Set[str] = set()
|
||||
dropped_tool_span_indices = _get_dropped_tool_span_indices(
|
||||
kept_indices=kept_indices, tool_exchange_spans=tool_exchange_spans
|
||||
)
|
||||
|
||||
for i, msg in enumerate(messages):
|
||||
for i, msg in enumerate(original_messages):
|
||||
if i in dropped_tool_span_indices:
|
||||
continue
|
||||
if i in kept_indices:
|
||||
# Use the truncated version if we made one, otherwise the original
|
||||
compressed_messages.append(truncated_overrides.get(i, msg))
|
||||
else:
|
||||
key = extract_key(msg, fallback_index=i, used_keys=used_keys)
|
||||
content = msg.get("content", "")
|
||||
if isinstance(content, list):
|
||||
content = " ".join(
|
||||
p.get("text", "") if isinstance(p, dict) else str(p)
|
||||
for p in content
|
||||
)
|
||||
key = extract_key(
|
||||
normalized_messages[i], fallback_index=i, used_keys=used_keys
|
||||
)
|
||||
content = _content_to_text(msg.get("content", ""))
|
||||
cache[key] = content
|
||||
compressed_messages.append(stub_message(msg, key))
|
||||
|
||||
# Build retrieval tool
|
||||
tools = [build_retrieval_tool(list(cache.keys()))] if cache else []
|
||||
# Build retrieval tool in the target request schema
|
||||
tools = _build_retrieval_tools(list(cache.keys()), call_type=call_type_str)
|
||||
|
||||
compressed_tokens = token_counter(
|
||||
model=model,
|
||||
messages=cast(List[Union[AllMessageValues, Message]], compressed_messages),
|
||||
messages=cast(List[Any], compressed_messages),
|
||||
)
|
||||
|
||||
return CompressedResult(
|
||||
messages=compressed_messages,
|
||||
original_tokens=original_tokens,
|
||||
compressed_tokens=compressed_tokens,
|
||||
compression_ratio=round(1 - (compressed_tokens / original_tokens), 4)
|
||||
if original_tokens > 0
|
||||
else 0.0,
|
||||
compression_ratio=(
|
||||
round(1 - (compressed_tokens / original_tokens), 4)
|
||||
if original_tokens > 0
|
||||
else 0.0
|
||||
),
|
||||
cache=cache,
|
||||
tools=tools,
|
||||
)
|
||||
|
|
|
|||
|
|
@ -164,6 +164,7 @@ MCP_STDIO_ALLOWED_COMMANDS: frozenset = frozenset(
|
|||
LITELLM_UI_ALLOW_HEADERS = [
|
||||
"x-litellm-semantic-filter",
|
||||
"x-litellm-semantic-filter-tools",
|
||||
"x-litellm-adaptive-router-model",
|
||||
]
|
||||
|
||||
# Gemini model-specific minimal thinking budget constants
|
||||
|
|
@ -1360,6 +1361,25 @@ try:
|
|||
)
|
||||
except (ValueError, TypeError):
|
||||
BACKGROUND_HEALTH_CHECK_MAX_TOKENS = None
|
||||
|
||||
|
||||
_background_health_check_max_tokens_reasoning_env = os.getenv(
|
||||
"BACKGROUND_HEALTH_CHECK_MAX_TOKENS_REASONING"
|
||||
)
|
||||
try:
|
||||
_raw_background_health_check_max_tokens_reasoning = (
|
||||
_background_health_check_max_tokens_reasoning_env.strip()
|
||||
if _background_health_check_max_tokens_reasoning_env is not None
|
||||
else ""
|
||||
)
|
||||
BACKGROUND_HEALTH_CHECK_MAX_TOKENS_REASONING: Optional[int] = (
|
||||
int(_raw_background_health_check_max_tokens_reasoning)
|
||||
if _raw_background_health_check_max_tokens_reasoning
|
||||
else None
|
||||
)
|
||||
except (ValueError, TypeError):
|
||||
BACKGROUND_HEALTH_CHECK_MAX_TOKENS_REASONING = None
|
||||
|
||||
LITTELM_INTERNAL_HEALTH_SERVICE_ACCOUNT_NAME = "litellm-internal-health-check"
|
||||
LITTELM_CLI_SERVICE_ACCOUNT_NAME = "litellm-cli"
|
||||
LITELLM_INTERNAL_JOBS_SERVICE_ACCOUNT_NAME = "litellm_internal_jobs"
|
||||
|
|
|
|||
|
|
@ -90,10 +90,10 @@ def create_sync_endpoint_function(endpoint_config: Dict) -> Callable:
|
|||
custom_llm_provider=resolved_custom_llm_provider,
|
||||
litellm_params=litellm_params,
|
||||
)
|
||||
container_provider_config: Optional[
|
||||
BaseContainerConfig
|
||||
] = ProviderConfigManager.get_provider_container_config(
|
||||
provider=litellm.LlmProviders(resolved_custom_llm_provider),
|
||||
container_provider_config: Optional[BaseContainerConfig] = (
|
||||
ProviderConfigManager.get_provider_container_config(
|
||||
provider=litellm.LlmProviders(resolved_custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if container_provider_config is None:
|
||||
|
|
|
|||
|
|
@ -168,7 +168,10 @@ def create_container(
|
|||
extra_query: Optional[Dict[str, Any]] = None,
|
||||
extra_body: Optional[Dict[str, Any]] = None,
|
||||
**kwargs,
|
||||
) -> Union[ContainerObject, Coroutine[Any, Any, ContainerObject],]:
|
||||
) -> Union[
|
||||
ContainerObject,
|
||||
Coroutine[Any, Any, ContainerObject],
|
||||
]:
|
||||
"""Create a container using the OpenAI Container API.
|
||||
|
||||
Currently supports OpenAI
|
||||
|
|
@ -208,10 +211,10 @@ def create_container(
|
|||
**kwargs,
|
||||
)
|
||||
# get provider config
|
||||
container_provider_config: Optional[
|
||||
BaseContainerConfig
|
||||
] = ProviderConfigManager.get_provider_container_config(
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
container_provider_config: Optional[BaseContainerConfig] = (
|
||||
ProviderConfigManager.get_provider_container_config(
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if container_provider_config is None:
|
||||
|
|
@ -260,7 +263,7 @@ def create_container(
|
|||
timeout=timeout or DEFAULT_REQUEST_TIMEOUT,
|
||||
_is_async=_is_async,
|
||||
)
|
||||
|
||||
|
||||
# Encode container_id with provider/model metadata for routing
|
||||
if isinstance(container_obj, ContainerObject):
|
||||
container_obj = ContainerRequestUtils.encode_container_id_in_response(
|
||||
|
|
@ -269,7 +272,7 @@ def create_container(
|
|||
litellm_metadata=kwargs.get("litellm_metadata"),
|
||||
extra_body=extra_body,
|
||||
)
|
||||
|
||||
|
||||
return container_obj
|
||||
|
||||
except Exception as e:
|
||||
|
|
@ -405,7 +408,10 @@ def list_containers(
|
|||
extra_query: Optional[Dict[str, Any]] = None,
|
||||
extra_body: Optional[Dict[str, Any]] = None,
|
||||
**kwargs,
|
||||
) -> Union[ContainerListResponse, Coroutine[Any, Any, ContainerListResponse],]:
|
||||
) -> Union[
|
||||
ContainerListResponse,
|
||||
Coroutine[Any, Any, ContainerListResponse],
|
||||
]:
|
||||
"""List containers using the OpenAI Container API.
|
||||
|
||||
Currently supports OpenAI
|
||||
|
|
@ -434,10 +440,10 @@ def list_containers(
|
|||
**kwargs,
|
||||
)
|
||||
# get provider config
|
||||
container_provider_config: Optional[
|
||||
BaseContainerConfig
|
||||
] = ProviderConfigManager.get_provider_container_config(
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
container_provider_config: Optional[BaseContainerConfig] = (
|
||||
ProviderConfigManager.get_provider_container_config(
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if container_provider_config is None:
|
||||
|
|
@ -601,7 +607,10 @@ def retrieve_container(
|
|||
extra_query: Optional[Dict[str, Any]] = None,
|
||||
extra_body: Optional[Dict[str, Any]] = None,
|
||||
**kwargs,
|
||||
) -> Union[ContainerObject, Coroutine[Any, Any, ContainerObject],]:
|
||||
) -> Union[
|
||||
ContainerObject,
|
||||
Coroutine[Any, Any, ContainerObject],
|
||||
]:
|
||||
"""Retrieve a container using the OpenAI Container API.
|
||||
|
||||
Currently supports OpenAI
|
||||
|
|
@ -630,7 +639,7 @@ def retrieve_container(
|
|||
api_version=api_version,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
|
||||
# Decode container ID and extract provider info
|
||||
original_container_id, resolved_custom_llm_provider, litellm_params = (
|
||||
decode_managed_container_id_for_request(
|
||||
|
|
@ -643,10 +652,10 @@ def retrieve_container(
|
|||
was_encoded = original_container_id != container_id
|
||||
|
||||
# get provider config
|
||||
container_provider_config: Optional[
|
||||
BaseContainerConfig
|
||||
] = ProviderConfigManager.get_provider_container_config(
|
||||
provider=litellm.LlmProviders(resolved_custom_llm_provider),
|
||||
container_provider_config: Optional[BaseContainerConfig] = (
|
||||
ProviderConfigManager.get_provider_container_config(
|
||||
provider=litellm.LlmProviders(resolved_custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if container_provider_config is None:
|
||||
|
|
@ -678,7 +687,7 @@ def retrieve_container(
|
|||
timeout=timeout or DEFAULT_REQUEST_TIMEOUT,
|
||||
_is_async=_is_async,
|
||||
)
|
||||
|
||||
|
||||
# Encode container_id with provider/model metadata for routing
|
||||
# If input was encoded, preserve encoding in output using the decoded model_id
|
||||
if isinstance(container_obj, ContainerObject):
|
||||
|
|
@ -691,14 +700,14 @@ def retrieve_container(
|
|||
if "model_info" not in litellm_metadata:
|
||||
litellm_metadata["model_info"] = {}
|
||||
litellm_metadata["model_info"]["id"] = litellm_params["model_id"]
|
||||
|
||||
|
||||
container_obj = ContainerRequestUtils.encode_container_id_in_response(
|
||||
response_obj=container_obj,
|
||||
custom_llm_provider=resolved_custom_llm_provider,
|
||||
litellm_metadata=litellm_metadata,
|
||||
extra_body=None,
|
||||
)
|
||||
|
||||
|
||||
return container_obj
|
||||
|
||||
except Exception as e:
|
||||
|
|
@ -822,7 +831,10 @@ def delete_container(
|
|||
extra_query: Optional[Dict[str, Any]] = None,
|
||||
extra_body: Optional[Dict[str, Any]] = None,
|
||||
**kwargs,
|
||||
) -> Union[DeleteContainerResult, Coroutine[Any, Any, DeleteContainerResult],]:
|
||||
) -> Union[
|
||||
DeleteContainerResult,
|
||||
Coroutine[Any, Any, DeleteContainerResult],
|
||||
]:
|
||||
"""Delete a container using the OpenAI Container API.
|
||||
|
||||
Currently supports OpenAI
|
||||
|
|
@ -851,7 +863,7 @@ def delete_container(
|
|||
api_version=api_version,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
|
||||
# Decode container ID and extract provider info
|
||||
original_container_id, resolved_custom_llm_provider, litellm_params = (
|
||||
decode_managed_container_id_for_request(
|
||||
|
|
@ -864,10 +876,10 @@ def delete_container(
|
|||
was_encoded = original_container_id != container_id
|
||||
|
||||
# get provider config
|
||||
container_provider_config: Optional[
|
||||
BaseContainerConfig
|
||||
] = ProviderConfigManager.get_provider_container_config(
|
||||
provider=litellm.LlmProviders(resolved_custom_llm_provider),
|
||||
container_provider_config: Optional[BaseContainerConfig] = (
|
||||
ProviderConfigManager.get_provider_container_config(
|
||||
provider=litellm.LlmProviders(resolved_custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if container_provider_config is None:
|
||||
|
|
@ -899,7 +911,7 @@ def delete_container(
|
|||
timeout=timeout or DEFAULT_REQUEST_TIMEOUT,
|
||||
_is_async=_is_async,
|
||||
)
|
||||
|
||||
|
||||
# Encode container_id in response with provider/model metadata for routing
|
||||
# If input was encoded, preserve encoding in output using the decoded model_id
|
||||
if isinstance(delete_result, DeleteContainerResult):
|
||||
|
|
@ -912,14 +924,14 @@ def delete_container(
|
|||
if "model_info" not in litellm_metadata:
|
||||
litellm_metadata["model_info"] = {}
|
||||
litellm_metadata["model_info"]["id"] = litellm_params["model_id"]
|
||||
|
||||
|
||||
delete_result = ContainerRequestUtils.encode_container_id_in_response(
|
||||
response_obj=delete_result,
|
||||
custom_llm_provider=resolved_custom_llm_provider,
|
||||
litellm_metadata=litellm_metadata,
|
||||
extra_body=None,
|
||||
)
|
||||
|
||||
|
||||
return delete_result
|
||||
|
||||
except Exception as e:
|
||||
|
|
@ -1057,7 +1069,10 @@ def list_container_files(
|
|||
extra_query: Optional[Dict[str, Any]] = None,
|
||||
extra_body: Optional[Dict[str, Any]] = None,
|
||||
**kwargs,
|
||||
) -> Union[ContainerFileListResponse, Coroutine[Any, Any, ContainerFileListResponse],]:
|
||||
) -> Union[
|
||||
ContainerFileListResponse,
|
||||
Coroutine[Any, Any, ContainerFileListResponse],
|
||||
]:
|
||||
"""List files in a container using the OpenAI Container API.
|
||||
|
||||
Currently supports OpenAI
|
||||
|
|
@ -1086,7 +1101,7 @@ def list_container_files(
|
|||
api_version=api_version,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
|
||||
# Decode container ID and extract provider info
|
||||
original_container_id, resolved_custom_llm_provider, litellm_params = (
|
||||
decode_managed_container_id_for_request(
|
||||
|
|
@ -1095,12 +1110,12 @@ def list_container_files(
|
|||
litellm_params=litellm_params,
|
||||
)
|
||||
)
|
||||
|
||||
|
||||
# get provider config
|
||||
container_provider_config: Optional[
|
||||
BaseContainerConfig
|
||||
] = ProviderConfigManager.get_provider_container_config(
|
||||
provider=litellm.LlmProviders(resolved_custom_llm_provider),
|
||||
container_provider_config: Optional[BaseContainerConfig] = (
|
||||
ProviderConfigManager.get_provider_container_config(
|
||||
provider=litellm.LlmProviders(resolved_custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if container_provider_config is None:
|
||||
|
|
@ -1285,7 +1300,10 @@ def upload_container_file(
|
|||
extra_query: Optional[Dict[str, Any]] = None,
|
||||
extra_body: Optional[Dict[str, Any]] = None,
|
||||
**kwargs,
|
||||
) -> Union[ContainerFileObject, Coroutine[Any, Any, ContainerFileObject],]:
|
||||
) -> Union[
|
||||
ContainerFileObject,
|
||||
Coroutine[Any, Any, ContainerFileObject],
|
||||
]:
|
||||
"""Upload a file to a container using the OpenAI Container API.
|
||||
|
||||
This endpoint allows uploading files directly to a container session,
|
||||
|
|
@ -1343,7 +1361,7 @@ def upload_container_file(
|
|||
api_version=api_version,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
|
||||
# Decode container ID and extract provider info
|
||||
original_container_id, resolved_custom_llm_provider, litellm_params = (
|
||||
decode_managed_container_id_for_request(
|
||||
|
|
@ -1352,12 +1370,12 @@ def upload_container_file(
|
|||
litellm_params=litellm_params,
|
||||
)
|
||||
)
|
||||
|
||||
|
||||
# get provider config
|
||||
container_provider_config: Optional[
|
||||
BaseContainerConfig
|
||||
] = ProviderConfigManager.get_provider_container_config(
|
||||
provider=litellm.LlmProviders(resolved_custom_llm_provider),
|
||||
container_provider_config: Optional[BaseContainerConfig] = (
|
||||
ProviderConfigManager.get_provider_container_config(
|
||||
provider=litellm.LlmProviders(resolved_custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if container_provider_config is None:
|
||||
|
|
|
|||
|
|
@ -32,6 +32,7 @@ def decode_managed_container_id_for_request(
|
|||
|
||||
return original_container_id, custom_llm_provider, litellm_params
|
||||
|
||||
|
||||
T = TypeVar("T")
|
||||
|
||||
|
||||
|
|
@ -129,14 +130,14 @@ class ContainerRequestUtils:
|
|||
litellm_metadata = litellm_metadata or {}
|
||||
model_info: Dict[str, Any] = litellm_metadata.get("model_info", {}) or {}
|
||||
model_id = model_info.get("id")
|
||||
|
||||
|
||||
# Check if we should encode based on routing metadata
|
||||
should_encode = False
|
||||
|
||||
|
||||
# Case 1: Router/proxy usage (model_id from router)
|
||||
if model_id is not None:
|
||||
should_encode = True
|
||||
|
||||
|
||||
# Case 2: target_model_names in extra_body (model-specific routing)
|
||||
if extra_body and "target_model_names" in extra_body:
|
||||
should_encode = True
|
||||
|
|
@ -148,7 +149,7 @@ class ContainerRequestUtils:
|
|||
model_id = target_models.split(",")[0].strip()
|
||||
elif isinstance(target_models, list) and len(target_models) > 0:
|
||||
model_id = str(target_models[0]).strip()
|
||||
|
||||
|
||||
# Only encode if we have routing metadata
|
||||
if should_encode and response_obj and hasattr(response_obj, "id"):
|
||||
encoded_id = ResponsesAPIRequestUtils._build_container_id(
|
||||
|
|
|
|||
|
|
@ -545,10 +545,9 @@ def cost_per_token( # noqa: PLR0915
|
|||
model=model, custom_llm_provider=custom_llm_provider
|
||||
)
|
||||
|
||||
if (
|
||||
(model_info.get("input_cost_per_token") or 0.0) > 0
|
||||
or (model_info.get("output_cost_per_token") or 0.0) > 0
|
||||
):
|
||||
if (model_info.get("input_cost_per_token") or 0.0) > 0 or (
|
||||
model_info.get("output_cost_per_token") or 0.0
|
||||
) > 0:
|
||||
return generic_cost_per_token(
|
||||
model=model,
|
||||
usage=usage_block,
|
||||
|
|
@ -1141,9 +1140,9 @@ def completion_cost( # noqa: PLR0915
|
|||
or isinstance(completion_response, dict)
|
||||
): # tts returns a custom class
|
||||
if isinstance(completion_response, dict):
|
||||
usage_obj: Optional[
|
||||
Union[dict, Usage]
|
||||
] = completion_response.get("usage", {})
|
||||
usage_obj: Optional[Union[dict, Usage]] = (
|
||||
completion_response.get("usage", {})
|
||||
)
|
||||
else:
|
||||
usage_obj = getattr(completion_response, "usage", {})
|
||||
if isinstance(usage_obj, BaseModel) and not _is_known_usage_objects(
|
||||
|
|
@ -1606,11 +1605,23 @@ def completion_cost( # noqa: PLR0915
|
|||
_cache_read_cost: Optional[float] = None
|
||||
_cache_creation_cost: Optional[float] = None
|
||||
if cost_per_token_usage_object is not None:
|
||||
_cr = getattr(cost_per_token_usage_object, "cache_read_input_tokens", None) or (cost_per_token_usage_object.model_extra or {}).get("cache_read_input_tokens")
|
||||
_cc = getattr(cost_per_token_usage_object, "cache_creation_input_tokens", None) or (cost_per_token_usage_object.model_extra or {}).get("cache_creation_input_tokens")
|
||||
_cr = getattr(
|
||||
cost_per_token_usage_object, "cache_read_input_tokens", None
|
||||
) or (cost_per_token_usage_object.model_extra or {}).get(
|
||||
"cache_read_input_tokens"
|
||||
)
|
||||
_cc = getattr(
|
||||
cost_per_token_usage_object,
|
||||
"cache_creation_input_tokens",
|
||||
None,
|
||||
) or (cost_per_token_usage_object.model_extra or {}).get(
|
||||
"cache_creation_input_tokens"
|
||||
)
|
||||
if (_cr or _cc) and model:
|
||||
try:
|
||||
_mi = litellm.get_model_info(model=model, custom_llm_provider=custom_llm_provider)
|
||||
_mi = litellm.get_model_info(
|
||||
model=model, custom_llm_provider=custom_llm_provider
|
||||
)
|
||||
_cr_rate = _mi.get("cache_read_input_token_cost")
|
||||
if _cr and _cr_rate is not None:
|
||||
_cache_read_cost = float(_cr) * float(_cr_rate)
|
||||
|
|
|
|||
|
|
@ -152,10 +152,10 @@ def create_eval(
|
|||
custom_llm_provider = "openai"
|
||||
|
||||
# Get provider config
|
||||
evals_api_provider_config: Optional[
|
||||
BaseEvalsAPIConfig
|
||||
] = ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
evals_api_provider_config: Optional[BaseEvalsAPIConfig] = (
|
||||
ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if evals_api_provider_config is None:
|
||||
|
|
@ -343,10 +343,10 @@ def list_evals(
|
|||
custom_llm_provider = "openai"
|
||||
|
||||
# Get provider config
|
||||
evals_api_provider_config: Optional[
|
||||
BaseEvalsAPIConfig
|
||||
] = ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
evals_api_provider_config: Optional[BaseEvalsAPIConfig] = (
|
||||
ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if evals_api_provider_config is None:
|
||||
|
|
@ -513,10 +513,10 @@ def get_eval(
|
|||
custom_llm_provider = "openai"
|
||||
|
||||
# Get provider config
|
||||
evals_api_provider_config: Optional[
|
||||
BaseEvalsAPIConfig
|
||||
] = ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
evals_api_provider_config: Optional[BaseEvalsAPIConfig] = (
|
||||
ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if evals_api_provider_config is None:
|
||||
|
|
@ -682,10 +682,10 @@ def update_eval(
|
|||
custom_llm_provider = "openai"
|
||||
|
||||
# Get provider config
|
||||
evals_api_provider_config: Optional[
|
||||
BaseEvalsAPIConfig
|
||||
] = ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
evals_api_provider_config: Optional[BaseEvalsAPIConfig] = (
|
||||
ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if evals_api_provider_config is None:
|
||||
|
|
@ -893,10 +893,10 @@ def delete_eval(
|
|||
custom_llm_provider = "openai"
|
||||
|
||||
# Get provider config
|
||||
evals_api_provider_config: Optional[
|
||||
BaseEvalsAPIConfig
|
||||
] = ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
evals_api_provider_config: Optional[BaseEvalsAPIConfig] = (
|
||||
ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if evals_api_provider_config is None:
|
||||
|
|
@ -1047,10 +1047,10 @@ def cancel_eval(
|
|||
custom_llm_provider = "openai"
|
||||
|
||||
# Get provider config
|
||||
evals_api_provider_config: Optional[
|
||||
BaseEvalsAPIConfig
|
||||
] = ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
evals_api_provider_config: Optional[BaseEvalsAPIConfig] = (
|
||||
ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if evals_api_provider_config is None:
|
||||
|
|
@ -1230,10 +1230,10 @@ def create_run(
|
|||
custom_llm_provider = "openai"
|
||||
|
||||
# Get provider config
|
||||
evals_api_provider_config: Optional[
|
||||
BaseEvalsAPIConfig
|
||||
] = ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
evals_api_provider_config: Optional[BaseEvalsAPIConfig] = (
|
||||
ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if evals_api_provider_config is None:
|
||||
|
|
@ -1418,10 +1418,10 @@ def list_runs(
|
|||
custom_llm_provider = "openai"
|
||||
|
||||
# Get provider config
|
||||
evals_api_provider_config: Optional[
|
||||
BaseEvalsAPIConfig
|
||||
] = ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
evals_api_provider_config: Optional[BaseEvalsAPIConfig] = (
|
||||
ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if evals_api_provider_config is None:
|
||||
|
|
@ -1592,10 +1592,10 @@ def get_run(
|
|||
custom_llm_provider = "openai"
|
||||
|
||||
# Get provider config
|
||||
evals_api_provider_config: Optional[
|
||||
BaseEvalsAPIConfig
|
||||
] = ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
evals_api_provider_config: Optional[BaseEvalsAPIConfig] = (
|
||||
ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if evals_api_provider_config is None:
|
||||
|
|
@ -1752,10 +1752,10 @@ def cancel_run(
|
|||
custom_llm_provider = "openai"
|
||||
|
||||
# Get provider config
|
||||
evals_api_provider_config: Optional[
|
||||
BaseEvalsAPIConfig
|
||||
] = ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
evals_api_provider_config: Optional[BaseEvalsAPIConfig] = (
|
||||
ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if evals_api_provider_config is None:
|
||||
|
|
@ -1921,10 +1921,10 @@ def delete_run(
|
|||
custom_llm_provider = "openai"
|
||||
|
||||
# Get provider config
|
||||
evals_api_provider_config: Optional[
|
||||
BaseEvalsAPIConfig
|
||||
] = ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
evals_api_provider_config: Optional[BaseEvalsAPIConfig] = (
|
||||
ProviderConfigManager.get_provider_evals_api_config( # type: ignore
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if evals_api_provider_config is None:
|
||||
|
|
|
|||
|
|
@ -281,7 +281,7 @@ class Timeout(openai.APITimeoutError): # type: ignore
|
|||
return _message
|
||||
|
||||
|
||||
class PermissionDeniedError(openai.PermissionDeniedError): # type:ignore
|
||||
class PermissionDeniedError(openai.PermissionDeniedError): # type: ignore
|
||||
def __init__(
|
||||
self,
|
||||
message,
|
||||
|
|
@ -847,6 +847,7 @@ class BudgetExceededError(Exception):
|
|||
):
|
||||
self.current_cost = current_cost
|
||||
self.max_budget = max_budget
|
||||
self.status_code = 429
|
||||
message = (
|
||||
message
|
||||
or f"Budget has been exceeded! Current cost: {current_cost}, Max budget: {max_budget}"
|
||||
|
|
|
|||
|
|
@ -10,7 +10,7 @@ import contextvars
|
|||
import time
|
||||
import uuid as uuid_module
|
||||
from functools import partial
|
||||
from typing import Any,Coroutine, Dict, Literal, Optional, Union, cast
|
||||
from typing import Any, Coroutine, Dict, Literal, Optional, Union, cast
|
||||
|
||||
import httpx
|
||||
|
||||
|
|
@ -53,7 +53,10 @@ from litellm.types.llms.openai import (
|
|||
OpenAIFileObject,
|
||||
)
|
||||
from litellm.types.router import *
|
||||
from litellm.types.utils import OPENAI_COMPATIBLE_BATCH_AND_FILES_PROVIDERS, LlmProviders
|
||||
from litellm.types.utils import (
|
||||
OPENAI_COMPATIBLE_BATCH_AND_FILES_PROVIDERS,
|
||||
LlmProviders,
|
||||
)
|
||||
from litellm.utils import (
|
||||
ProviderConfigManager,
|
||||
client,
|
||||
|
|
@ -73,6 +76,8 @@ def _should_sdk_support_streaming(
|
|||
Return whether file content streaming is supported for the provider.
|
||||
"""
|
||||
return custom_llm_provider in OPENAI_COMPATIBLE_BATCH_AND_FILES_PROVIDERS
|
||||
|
||||
|
||||
openai_files_instance = OpenAIFilesAPI()
|
||||
azure_files_instance = AzureOpenAIFilesAPI()
|
||||
vertex_ai_files_instance = VertexAIFilesHandler()
|
||||
|
|
@ -1094,9 +1099,10 @@ def file_content_streaming(
|
|||
)
|
||||
|
||||
if asyncio.iscoroutine(response):
|
||||
|
||||
async def _await_and_wrap() -> FileContentStreamingResult:
|
||||
return _wrap_streaming_result(await response)
|
||||
|
||||
return _await_and_wrap()
|
||||
|
||||
return _wrap_streaming_result(response)
|
||||
return _wrap_streaming_result(response)
|
||||
|
|
|
|||
|
|
@ -1,6 +1,15 @@
|
|||
import datetime
|
||||
import traceback
|
||||
from typing import TYPE_CHECKING, Any, AsyncIterator, Dict, Iterator, Optional, Union, cast
|
||||
from typing import (
|
||||
TYPE_CHECKING,
|
||||
Any,
|
||||
AsyncIterator,
|
||||
Dict,
|
||||
Iterator,
|
||||
Optional,
|
||||
Union,
|
||||
cast,
|
||||
)
|
||||
|
||||
import anyio
|
||||
from litellm.files.types import FileContentProvider
|
||||
|
|
@ -11,6 +20,7 @@ if TYPE_CHECKING:
|
|||
)
|
||||
from litellm.types.utils import StandardLoggingHiddenParams, StandardLoggingPayload
|
||||
|
||||
|
||||
class FileContentStreamingResponse:
|
||||
"""
|
||||
Iterator wrapper for file content streaming that carries LiteLLM metadata
|
||||
|
|
@ -84,7 +94,9 @@ class FileContentStreamingResponse:
|
|||
self._close_completed = True
|
||||
self._logging_completed = True
|
||||
stream_to_close = self.stream_iterator
|
||||
self.stream_iterator = cast(Union[Iterator[bytes], AsyncIterator[bytes]], iter(()))
|
||||
self.stream_iterator = cast(
|
||||
Union[Iterator[bytes], AsyncIterator[bytes]], iter(())
|
||||
)
|
||||
|
||||
# Shield cleanup from request cancellation so upstream HTTP connections
|
||||
# are released promptly on client disconnects.
|
||||
|
|
@ -103,7 +115,9 @@ class FileContentStreamingResponse:
|
|||
self._close_completed = True
|
||||
self._logging_completed = True
|
||||
stream_to_close = self.stream_iterator
|
||||
self.stream_iterator = cast(Union[Iterator[bytes], AsyncIterator[bytes]], iter(()))
|
||||
self.stream_iterator = cast(
|
||||
Union[Iterator[bytes], AsyncIterator[bytes]], iter(())
|
||||
)
|
||||
|
||||
if hasattr(stream_to_close, "close"):
|
||||
cast(Iterator[bytes], stream_to_close).close() # type: ignore[attr-defined]
|
||||
|
|
|
|||
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue