mirror of
https://github.com/BerriAI/litellm.git
synced 2026-10-09 03:18:44 +00:00
fix(proxy): return json error response instead of sse format for initial streaming errors (#18757)
* adding signoz integration to observability docs

* Fixing build

* Adding timeout for flaky test

* Fixing e2e

* fix(proxy): return json error response instead of sse format for initial streaming errors

when the first chunk of a streaming response contains an error,
return a standard json error response instead of sse format.
this ensures clients receive properly formatted error responses
before the stream actually begins.

- rename create_streaming_response to create_response
- add logic to detect error in first chunk and return JSONResponse
- add _extract_error_from_sse_chunk helper function
- update all call sites to use the new function name
- update tests to reflect the function rename

* test(proxy): add comprehensive tests for error extraction from sse chunks

- Add new test class TestExtractErrorFromSSEChunk with 10 test cases
- Update existing tests to verify JSONResponse returned for initial streaming errors
- Add tests for error code as string, bytes input, invalid JSON, and edge cases
- Verify correct error format extraction from SSE chunks

---------

Co-authored-by: Goutham Karthi <goutham@signoz.io>
Co-authored-by: yuneng-jiang <yuneng.jiang@gmail.com>
Co-authored-by: YutaSaito <36355491+uc4w6c@users.noreply.github.com>
This commit is contained in:
 Kris Xia
GitHub
parent
000913fa12
commit
91b5c66cf2
7 changed files with 616 additions and 58 deletions
394
docs/my-website/docs/observability/signoz.md
Normal file
394
docs/my-website/docs/observability/signoz.md
Normal file
|
|
@ -0,0 +1,394 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# SigNoz LiteLLM Integration
|
||||
|
||||
For more details on setting up observability for LiteLLM, check out the [SigNoz LiteLLM observability docs](https://signoz.io/docs/litellm-observability/).
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
This guide walks you through setting up observability and monitoring for LiteLLM SDK and Proxy Server using [OpenTelemetry](https://opentelemetry.io/) and exporting logs, traces, and metrics to SigNoz. With this integration, you can observe various models performance, capture request/response details, and track system-level metrics in SigNoz, giving you real-time visibility into latency, error rates, and usage trends for your LiteLLM applications.
|
||||
|
||||
Instrumenting LiteLLM in your AI applications with telemetry ensures full observability across your AI workflows, making it easier to debug issues, optimize performance, and understand user interactions. By leveraging SigNoz, you can analyze correlated traces, logs, and metrics in unified dashboards, configure alerts, and gain actionable insights to continuously improve reliability, responsiveness, and user experience.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
- A [SigNoz Cloud account](https://signoz.io/teams/) with an active ingestion key
|
||||
- Internet access to send telemetry data to SigNoz Cloud
|
||||
- [LiteLLM](https://www.litellm.ai/) SDK or Proxy integration
|
||||
- For Python: `pip` installed for managing Python packages and _(optional but recommended)_ a Python virtual environment to isolate dependencies
|
||||
|
||||
## Monitoring LiteLLM
|
||||
|
||||
LiteLLM can be monitored in two ways: using the **LiteLLM SDK** (directly embedded in your Python application code for programmatic LLM calls) or the **LiteLLM Proxy Server** (a standalone server that acts as a centralized gateway for managing and routing LLM requests across your infrastructure).
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="LiteLLM SDK" label="LiteLLM SDK" default>
|
||||
|
||||
For more detailed info on instrumenting your LiteLLM SDK applications click [here](https://docs.litellm.ai/docs/observability/opentelemetry_integration).
|
||||
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="No Code" label="No Code(Recommended)" default>
|
||||
|
||||
No-code auto-instrumentation is recommended for quick setup with minimal code changes. It's ideal when you want to get observability up and running without modifying your application code and are leveraging standard instrumentor libraries.
|
||||
|
||||
**Step 1:** Install the necessary packages in your Python environment.
|
||||
|
||||
```bash
|
||||
pip install \
|
||||
opentelemetry-api \
|
||||
opentelemetry-distro \
|
||||
opentelemetry-exporter-otlp \
|
||||
httpx \
|
||||
opentelemetry-instrumentation-httpx \
|
||||
litellm
|
||||
```
|
||||
|
||||
**Step 2:** Add Automatic Instrumentation
|
||||
|
||||
```bash
|
||||
opentelemetry-bootstrap --action=install
|
||||
```
|
||||
|
||||
**Step 3:** Instrument your LiteLLM SDK application
|
||||
|
||||
Initialize LiteLLM SDK instrumentation by calling `litellm.callbacks = ["otel"]`:
|
||||
|
||||
```python
|
||||
from litellm import litellm
|
||||
|
||||
litellm.callbacks = ["otel"]
|
||||
```
|
||||
|
||||
This call enables automatic tracing, logs, and metrics collection for all LiteLLM SDK calls in your application.
|
||||
|
||||
> 📌 Note: Ensure this is called before any LiteLLM related calls to properly configure instrumentation of your application
|
||||
|
||||
**Step 4:** Run an example
|
||||
|
||||
```python
|
||||
from litellm import completion, litellm
|
||||
|
||||
litellm.callbacks = ["otel"]
|
||||
|
||||
response = completion(
|
||||
model="openai/gpt-4o",
|
||||
messages=[{ "content": "What is SigNoz","role": "user"}]
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
> 📌 Note: LiteLLM supports a [variety of model providers](https://docs.litellm.ai/docs/providers) for LLMs. In this example, we're using OpenAI. Before running this code, ensure that you have set the environment variable `OPENAI_API_KEY` with your generated API key.
|
||||
|
||||
**Step 5:** Run your application with auto-instrumentation
|
||||
|
||||
```bash
|
||||
OTEL_RESOURCE_ATTRIBUTES="service.name=<service_name>" \
|
||||
OTEL_EXPORTER_OTLP_ENDPOINT="https://ingest.<region>.signoz.cloud:443" \
|
||||
OTEL_EXPORTER_OTLP_HEADERS="signoz-ingestion-key=<your_ingestion_key>" \
|
||||
OTEL_EXPORTER_OTLP_PROTOCOL=grpc \
|
||||
OTEL_TRACES_EXPORTER=otlp \
|
||||
OTEL_METRICS_EXPORTER=otlp \
|
||||
OTEL_LOGS_EXPORTER=otlp \
|
||||
OTEL_PYTHON_LOG_CORRELATION=true \
|
||||
OTEL_PYTHON_LOGGING_AUTO_INSTRUMENTATION_ENABLED=true \
|
||||
OTEL_PYTHON_DISABLED_INSTRUMENTATIONS=openai \
|
||||
opentelemetry-instrument <your_run_command>
|
||||
```
|
||||
|
||||
> 📌 Note: We're using `OTEL_PYTHON_DISABLED_INSTRUMENTATIONS=openai` in the run command to disable the OpenAI instrumentor for tracing. This avoids conflicts with LiteLLM's native telemetry/instrumentation, ensuring that telemetry is captured exclusively through LiteLLM's built-in instrumentation.
|
||||
|
||||
- **`<service_name>`** is the name of your service
|
||||
- Set the `<region>` to match your SigNoz Cloud [region](https://signoz.io/docs/ingestion/signoz-cloud/overview/#endpoint)
|
||||
- Replace `<your_ingestion_key>` with your SigNoz [ingestion key](https://signoz.io/docs/ingestion/signoz-cloud/keys/)
|
||||
- Replace `<your_run_command>` with the actual command you would use to run your application. For example: `python main.py`
|
||||
|
||||
> 📌 Note: Using self-hosted SigNoz? Most steps are identical. To adapt this guide, update the endpoint and remove the ingestion key header as shown in [Cloud → Self-Hosted](https://signoz.io/docs/ingestion/cloud-vs-self-hosted/#cloud-to-self-hosted).
|
||||
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="Code" label="Code" default>
|
||||
|
||||
Code-based instrumentation gives you fine-grained control over your telemetry configuration. Use this approach when you need to customize resource attributes, sampling strategies, or integrate with existing observability infrastructure.
|
||||
|
||||
**Step 1:** Install the necessary packages in your Python environment.
|
||||
|
||||
```bash
|
||||
pip install \
|
||||
opentelemetry-api \
|
||||
opentelemetry-sdk \
|
||||
opentelemetry-exporter-otlp \
|
||||
opentelemetry-instrumentation-httpx \
|
||||
opentelemetry-instrumentation-system-metrics \
|
||||
litellm
|
||||
```
|
||||
|
||||
**Step 2:** Import the necessary modules in your Python application
|
||||
|
||||
**Traces:**
|
||||
|
||||
```python
|
||||
from opentelemetry import trace
|
||||
from opentelemetry.sdk.resources import Resource
|
||||
from opentelemetry.sdk.trace import TracerProvider
|
||||
from opentelemetry.sdk.trace.export import BatchSpanProcessor
|
||||
from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter
|
||||
```
|
||||
|
||||
**Logs:**
|
||||
|
||||
```python
|
||||
from opentelemetry.sdk._logs import LoggerProvider, LoggingHandler
|
||||
from opentelemetry.sdk._logs.export import BatchLogRecordProcessor
|
||||
from opentelemetry.exporter.otlp.proto.http._log_exporter import OTLPLogExporter
|
||||
from opentelemetry._logs import set_logger_provider
|
||||
import logging
|
||||
```
|
||||
|
||||
**Metrics:**
|
||||
|
||||
```python
|
||||
from opentelemetry.sdk.metrics import MeterProvider
|
||||
from opentelemetry.exporter.otlp.proto.http.metric_exporter import OTLPMetricExporter
|
||||
from opentelemetry.sdk.metrics.export import PeriodicExportingMetricReader
|
||||
from opentelemetry import metrics
|
||||
from opentelemetry.instrumentation.system_metrics import SystemMetricsInstrumentor
|
||||
from opentelemetry.instrumentation.httpx import HTTPXClientInstrumentor
|
||||
```
|
||||
|
||||
**Step 3:** Set up the OpenTelemetry Tracer Provider to send traces directly to SigNoz Cloud
|
||||
|
||||
```python
|
||||
from opentelemetry.sdk.resources import Resource
|
||||
from opentelemetry.sdk.trace import TracerProvider
|
||||
from opentelemetry.sdk.trace.export import BatchSpanProcessor
|
||||
from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter
|
||||
from opentelemetry import trace
|
||||
import os
|
||||
|
||||
resource = Resource.create({"service.name": "<service_name>"})
|
||||
provider = TracerProvider(resource=resource)
|
||||
span_exporter = OTLPSpanExporter(
|
||||
endpoint= os.getenv("OTEL_EXPORTER_TRACES_ENDPOINT"),
|
||||
headers={"signoz-ingestion-key": os.getenv("SIGNOZ_INGESTION_KEY")},
|
||||
)
|
||||
processor = BatchSpanProcessor(span_exporter)
|
||||
provider.add_span_processor(processor)
|
||||
trace.set_tracer_provider(provider)
|
||||
```
|
||||
|
||||
- **`<service_name>`** is the name of your service
|
||||
- **`OTEL_EXPORTER_TRACES_ENDPOINT`** → SigNoz Cloud trace endpoint with appropriate [region](https://signoz.io/docs/ingestion/signoz-cloud/overview/#endpoint):`https://ingest.<region>.signoz.cloud:443/v1/traces`
|
||||
- **`SIGNOZ_INGESTION_KEY`** → Your SigNoz [ingestion key](https://signoz.io/docs/ingestion/signoz-cloud/keys/)
|
||||
|
||||
|
||||
> 📌 Note: Using self-hosted SigNoz? Most steps are identical. To adapt this guide, update the endpoint and remove the ingestion key header as shown in [Cloud → Self-Hosted](https://signoz.io/docs/ingestion/cloud-vs-self-hosted/#cloud-to-self-hosted).
|
||||
|
||||
|
||||
**Step 4**: Setup Logs
|
||||
|
||||
```python
|
||||
import logging
|
||||
from opentelemetry.sdk.resources import Resource
|
||||
from opentelemetry._logs import set_logger_provider
|
||||
from opentelemetry.sdk._logs import LoggerProvider, LoggingHandler
|
||||
from opentelemetry.sdk._logs.export import BatchLogRecordProcessor
|
||||
from opentelemetry.exporter.otlp.proto.http._log_exporter import OTLPLogExporter
|
||||
import os
|
||||
|
||||
resource = Resource.create({"service.name": "<service_name>"})
|
||||
logger_provider = LoggerProvider(resource=resource)
|
||||
set_logger_provider(logger_provider)
|
||||
|
||||
otlp_log_exporter = OTLPLogExporter(
|
||||
endpoint= os.getenv("OTEL_EXPORTER_LOGS_ENDPOINT"),
|
||||
headers={"signoz-ingestion-key": os.getenv("SIGNOZ_INGESTION_KEY")},
|
||||
)
|
||||
logger_provider.add_log_record_processor(
|
||||
BatchLogRecordProcessor(otlp_log_exporter)
|
||||
)
|
||||
# Attach OTel logging handler to root logger
|
||||
handler = LoggingHandler(level=logging.INFO, logger_provider=logger_provider)
|
||||
logging.basicConfig(level=logging.INFO, handlers=[handler])
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
```
|
||||
|
||||
- **`<service_name>`** is the name of your service
|
||||
- **`OTEL_EXPORTER_LOGS_ENDPOINT`** → SigNoz Cloud endpoint with appropriate [region](https://signoz.io/docs/ingestion/signoz-cloud/overview/#endpoint):`https://ingest.<region>.signoz.cloud:443/v1/logs`
|
||||
- **`SIGNOZ_INGESTION_KEY`** → Your SigNoz [ingestion key](https://signoz.io/docs/ingestion/signoz-cloud/keys/)
|
||||
|
||||
> 📌 Note: Using self-hosted SigNoz? Most steps are identical. To adapt this guide, update the endpoint and remove the ingestion key header as shown in [Cloud → Self-Hosted](https://signoz.io/docs/ingestion/cloud-vs-self-hosted/#cloud-to-self-hosted).
|
||||
|
||||
|
||||
**Step 5**: Setup Metrics
|
||||
|
||||
```python
|
||||
from opentelemetry.sdk.resources import Resource
|
||||
from opentelemetry.sdk.metrics import MeterProvider
|
||||
from opentelemetry.exporter.otlp.proto.http.metric_exporter import OTLPMetricExporter
|
||||
from opentelemetry.sdk.metrics.export import PeriodicExportingMetricReader
|
||||
from opentelemetry import metrics
|
||||
from opentelemetry.instrumentation.system_metrics import SystemMetricsInstrumentor
|
||||
import os
|
||||
|
||||
resource = Resource.create({"service.name": "<service-name>"})
|
||||
metric_exporter = OTLPMetricExporter(
|
||||
endpoint= os.getenv("OTEL_EXPORTER_METRICS_ENDPOINT"),
|
||||
headers={"signoz-ingestion-key": os.getenv("SIGNOZ_INGESTION_KEY")},
|
||||
)
|
||||
reader = PeriodicExportingMetricReader(metric_exporter)
|
||||
metric_provider = MeterProvider(metric_readers=[reader], resource=resource)
|
||||
metrics.set_meter_provider(metric_provider)
|
||||
|
||||
meter = metrics.get_meter(__name__)
|
||||
|
||||
# turn on out-of-the-box metrics
|
||||
SystemMetricsInstrumentor().instrument()
|
||||
HTTPXClientInstrumentor().instrument()
|
||||
```
|
||||
|
||||
- **`<service_name>`** is the name of your service
|
||||
- **`OTEL_EXPORTER_METRICS_ENDPOINT`** → SigNoz Cloud endpoint with appropriate [region](https://signoz.io/docs/ingestion/signoz-cloud/overview/#endpoint):`https://ingest.<region>.signoz.cloud:443/v1/metrics`
|
||||
- **`SIGNOZ_INGESTION_KEY`** → Your SigNoz [ingestion key](https://signoz.io/docs/ingestion/signoz-cloud/keys/)
|
||||
|
||||
> 📌 Note: Using self-hosted SigNoz? Most steps are identical. To adapt this guide, update the endpoint and remove the ingestion key header as shown in [Cloud → Self-Hosted](https://signoz.io/docs/ingestion/cloud-vs-self-hosted/#cloud-to-self-hosted).
|
||||
|
||||
|
||||
> 📌 Note: SystemMetricsInstrumentor provides system metrics (CPU, memory, etc.), and HTTPXClientInstrumentor provides outbound HTTP request metrics such as request duration. If you want to add custom metrics to your LiteLLM application, see [Python Custom Metrics](https://signoz.io/opentelemetry/python-custom-metrics/).
|
||||
|
||||
**Step 6:** Instrument your LiteLLM application
|
||||
|
||||
Initialize LiteLLM SDK instrumentation by calling `litellm.callbacks = ["otel"]`:
|
||||
|
||||
```python
|
||||
from litellm import litellm
|
||||
|
||||
litellm.callbacks = ["otel"]
|
||||
```
|
||||
|
||||
This call enables automatic tracing, logs, and metrics collection for all LiteLLM SDK calls in your application.
|
||||
|
||||
> 📌 Note: Ensure this is called before any LiteLLM related calls to properly configure instrumentation of your application
|
||||
|
||||
**Step 7:** Run an example
|
||||
|
||||
```python
|
||||
from litellm import completion, litellm
|
||||
|
||||
litellm.callbacks = ["otel"]
|
||||
|
||||
response = completion(
|
||||
model="openai/gpt-4o",
|
||||
messages=[{ "content": "What is SigNoz","role": "user"}]
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
> 📌 Note: LiteLLM supports a [variety of model providers](https://docs.litellm.ai/docs/providers) for LLMs. In this example, we're using OpenAI. Before running this code, ensure that you have set the environment variable `OPENAI_API_KEY` with your generated API key.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## View Traces, Logs, and Metrics in SigNoz
|
||||
|
||||
Your LiteLLM commands should now automatically emit traces, logs, and metrics.
|
||||
|
||||
You should be able to view traces in Signoz Cloud under the traces tab:
|
||||
|
||||
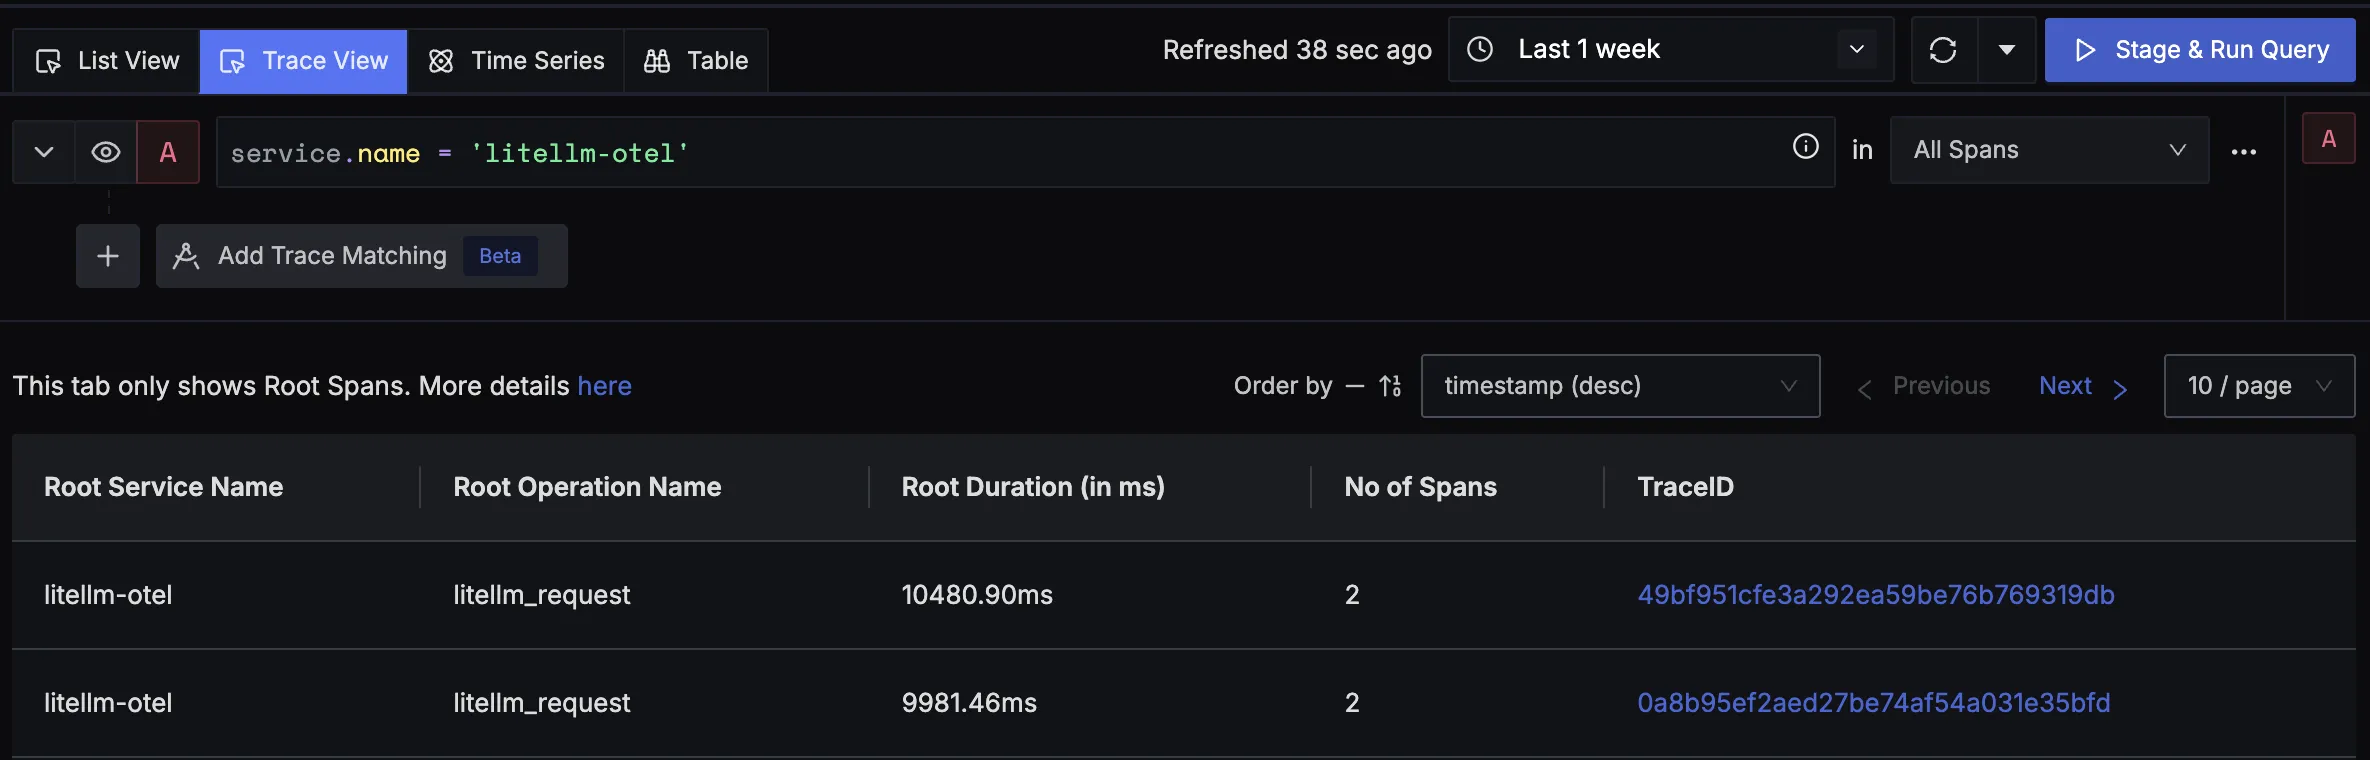
|
||||
|
||||
When you click on a trace in SigNoz, you'll see a detailed view of the trace, including all associated spans, along with their events and attributes.
|
||||
|
||||
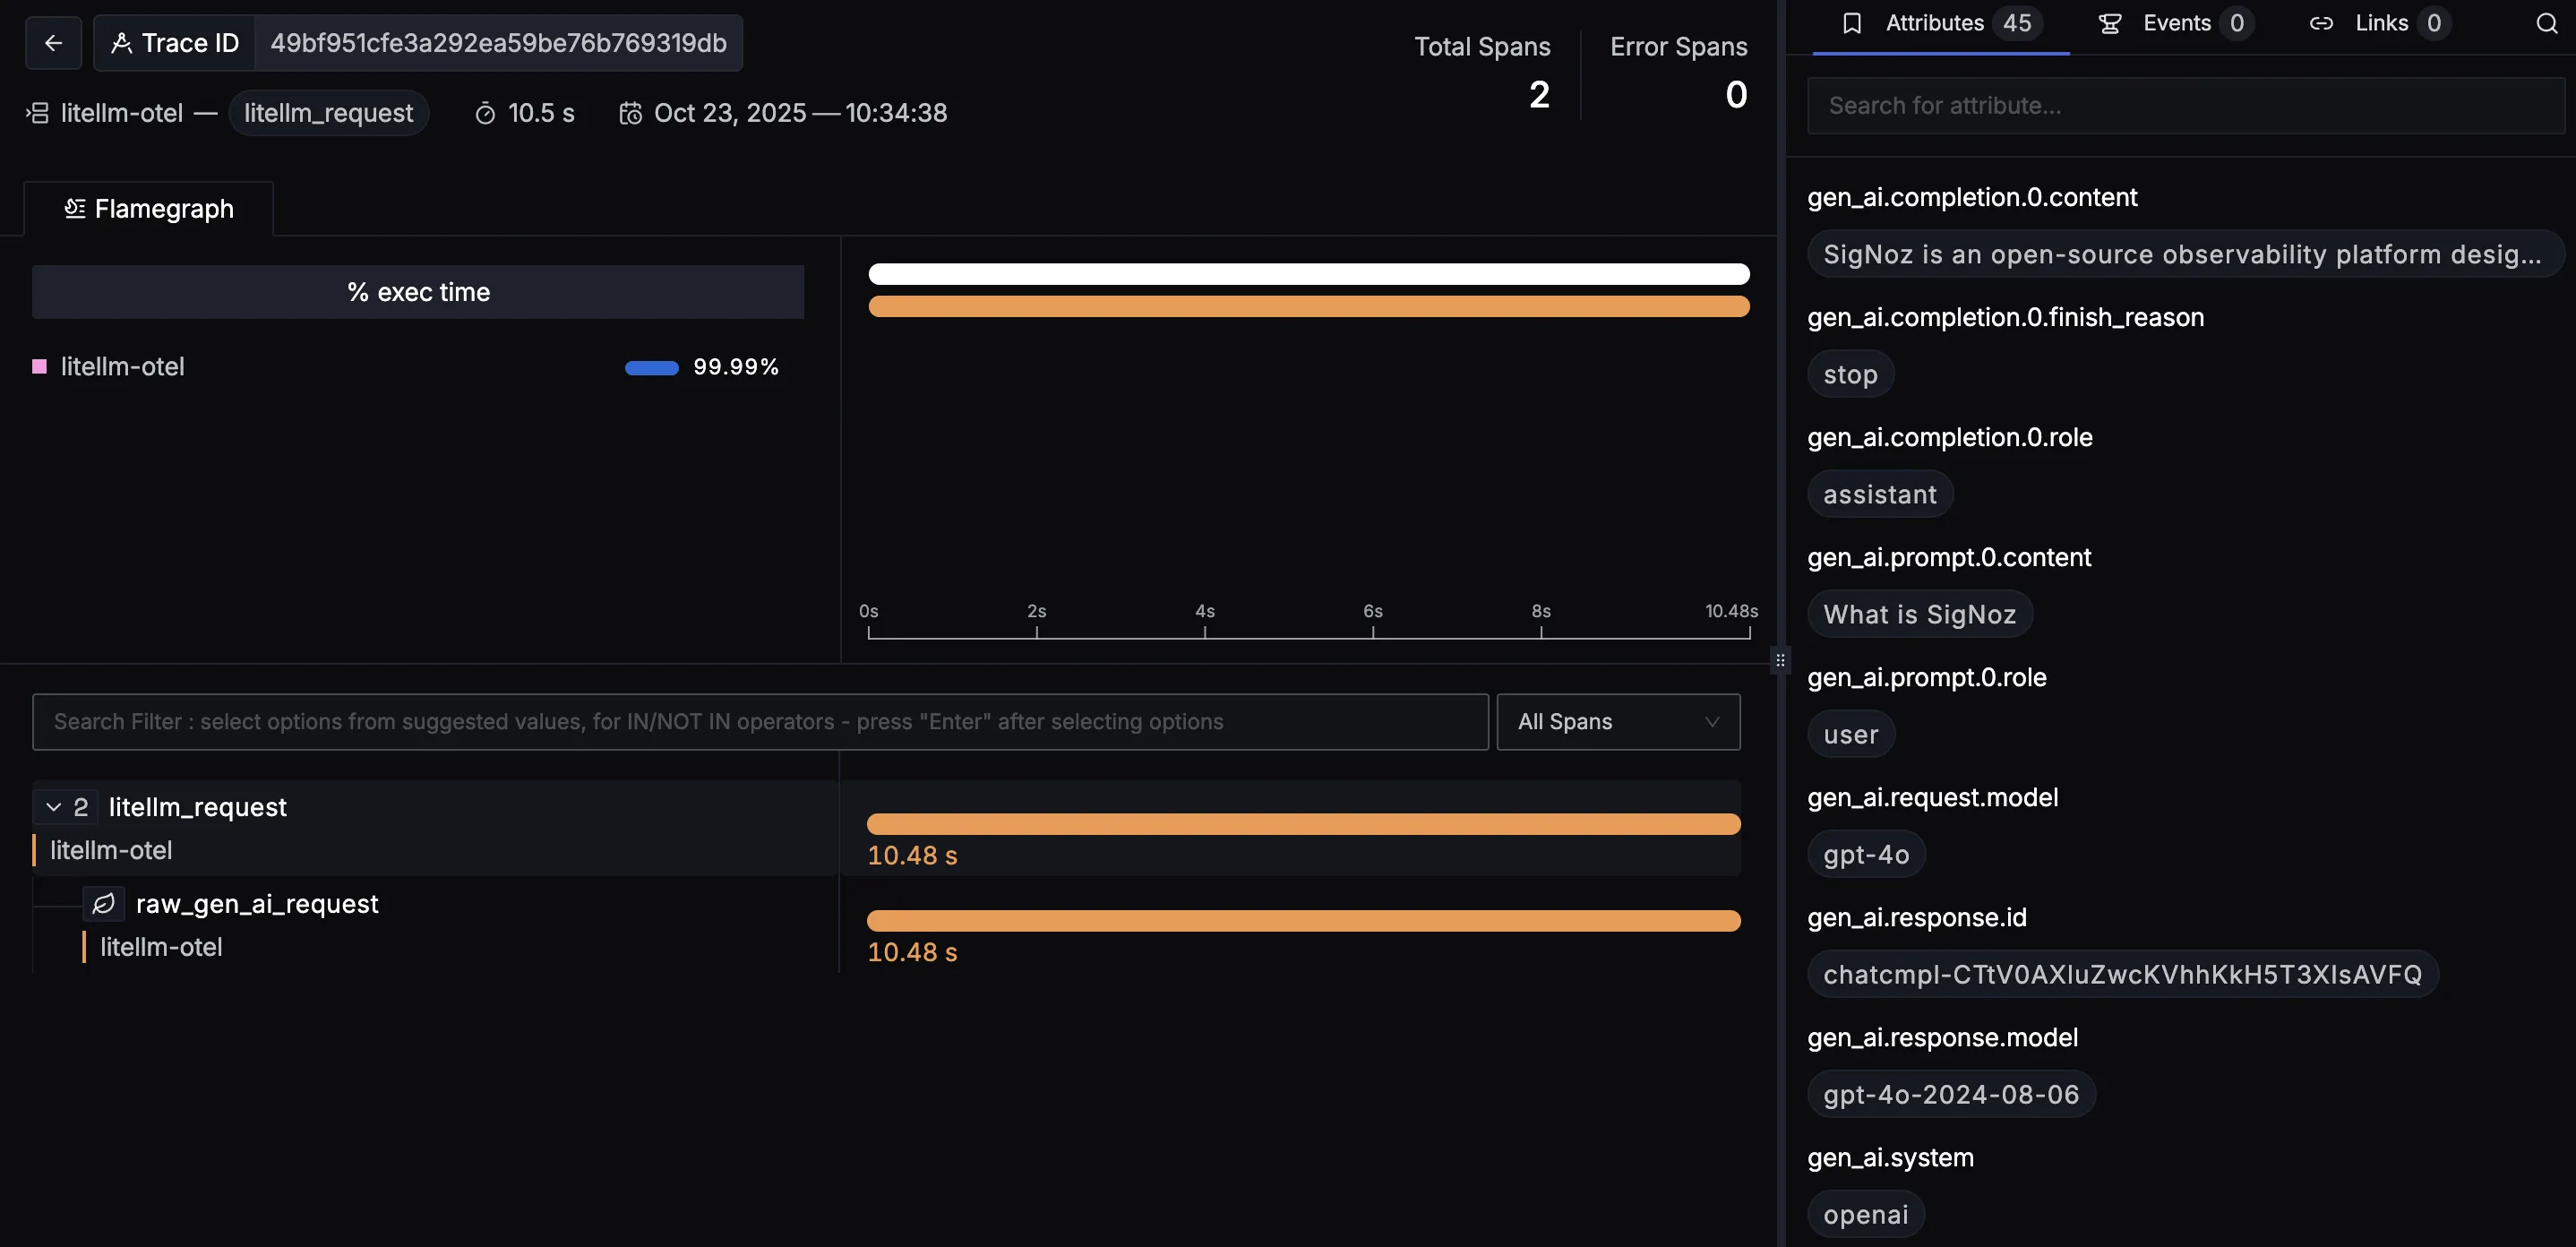
|
||||
|
||||
You should be able to view logs in Signoz Cloud under the logs tab. You can also view logs by clicking on the “Related Logs” button in the trace view to see correlated logs:
|
||||
|
||||
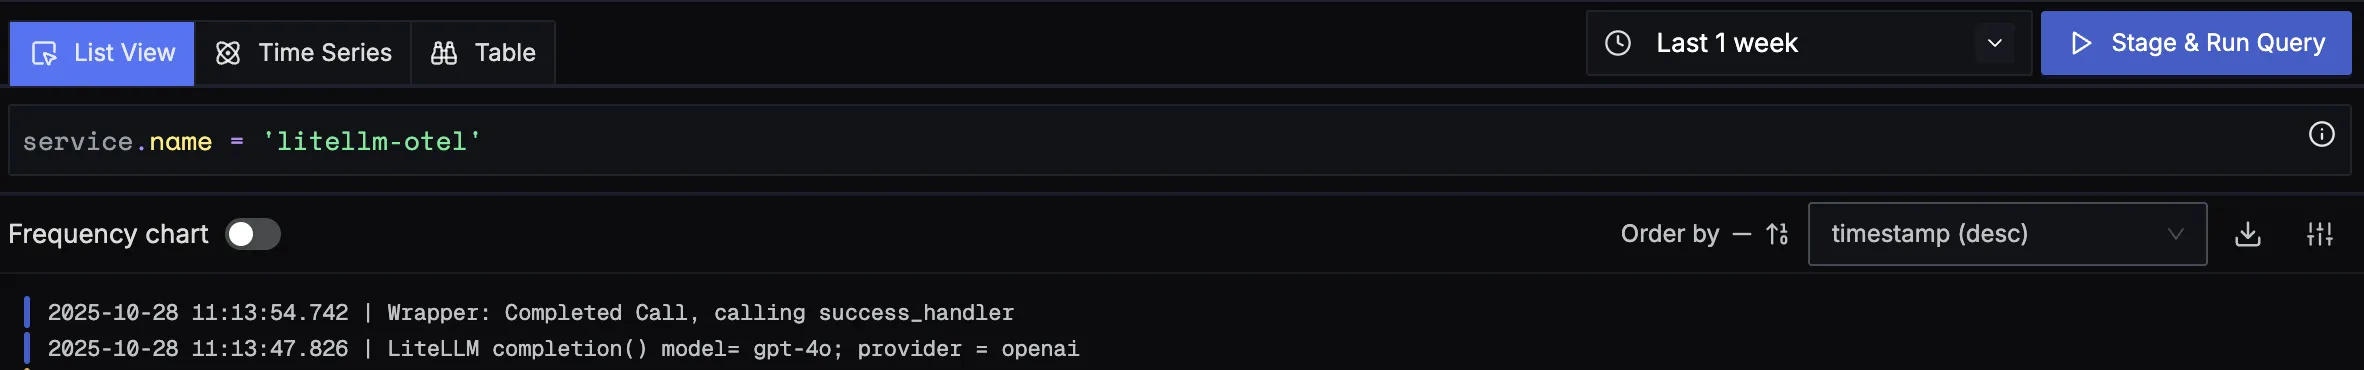
|
||||
|
||||
When you click on any of these logs in SigNoz, you'll see a detailed view of the log, including attributes:
|
||||
|
||||
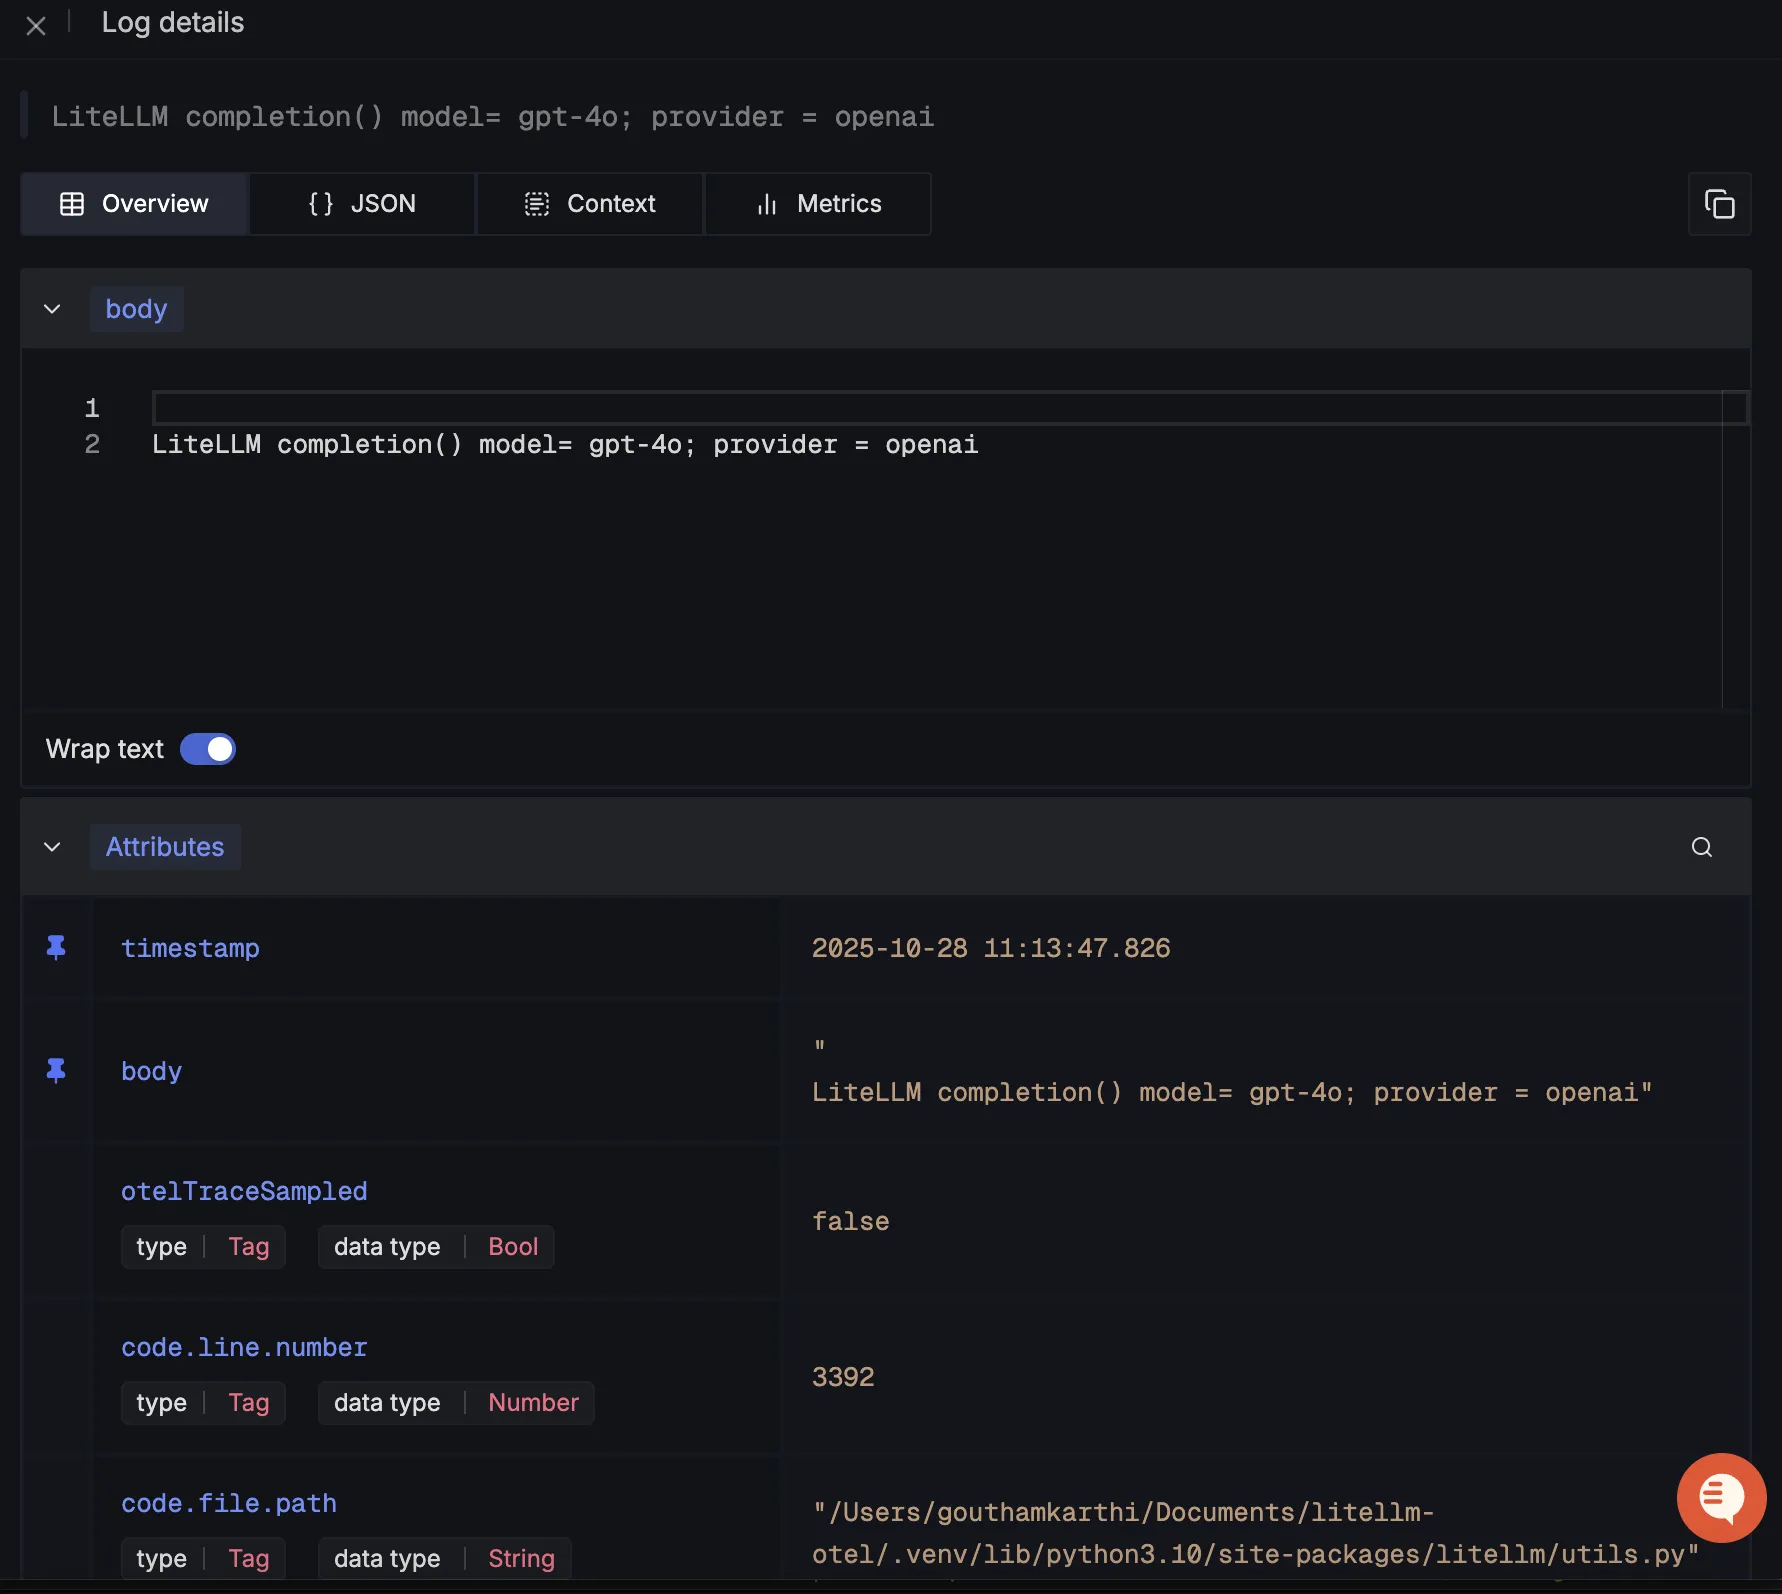
|
||||
|
||||
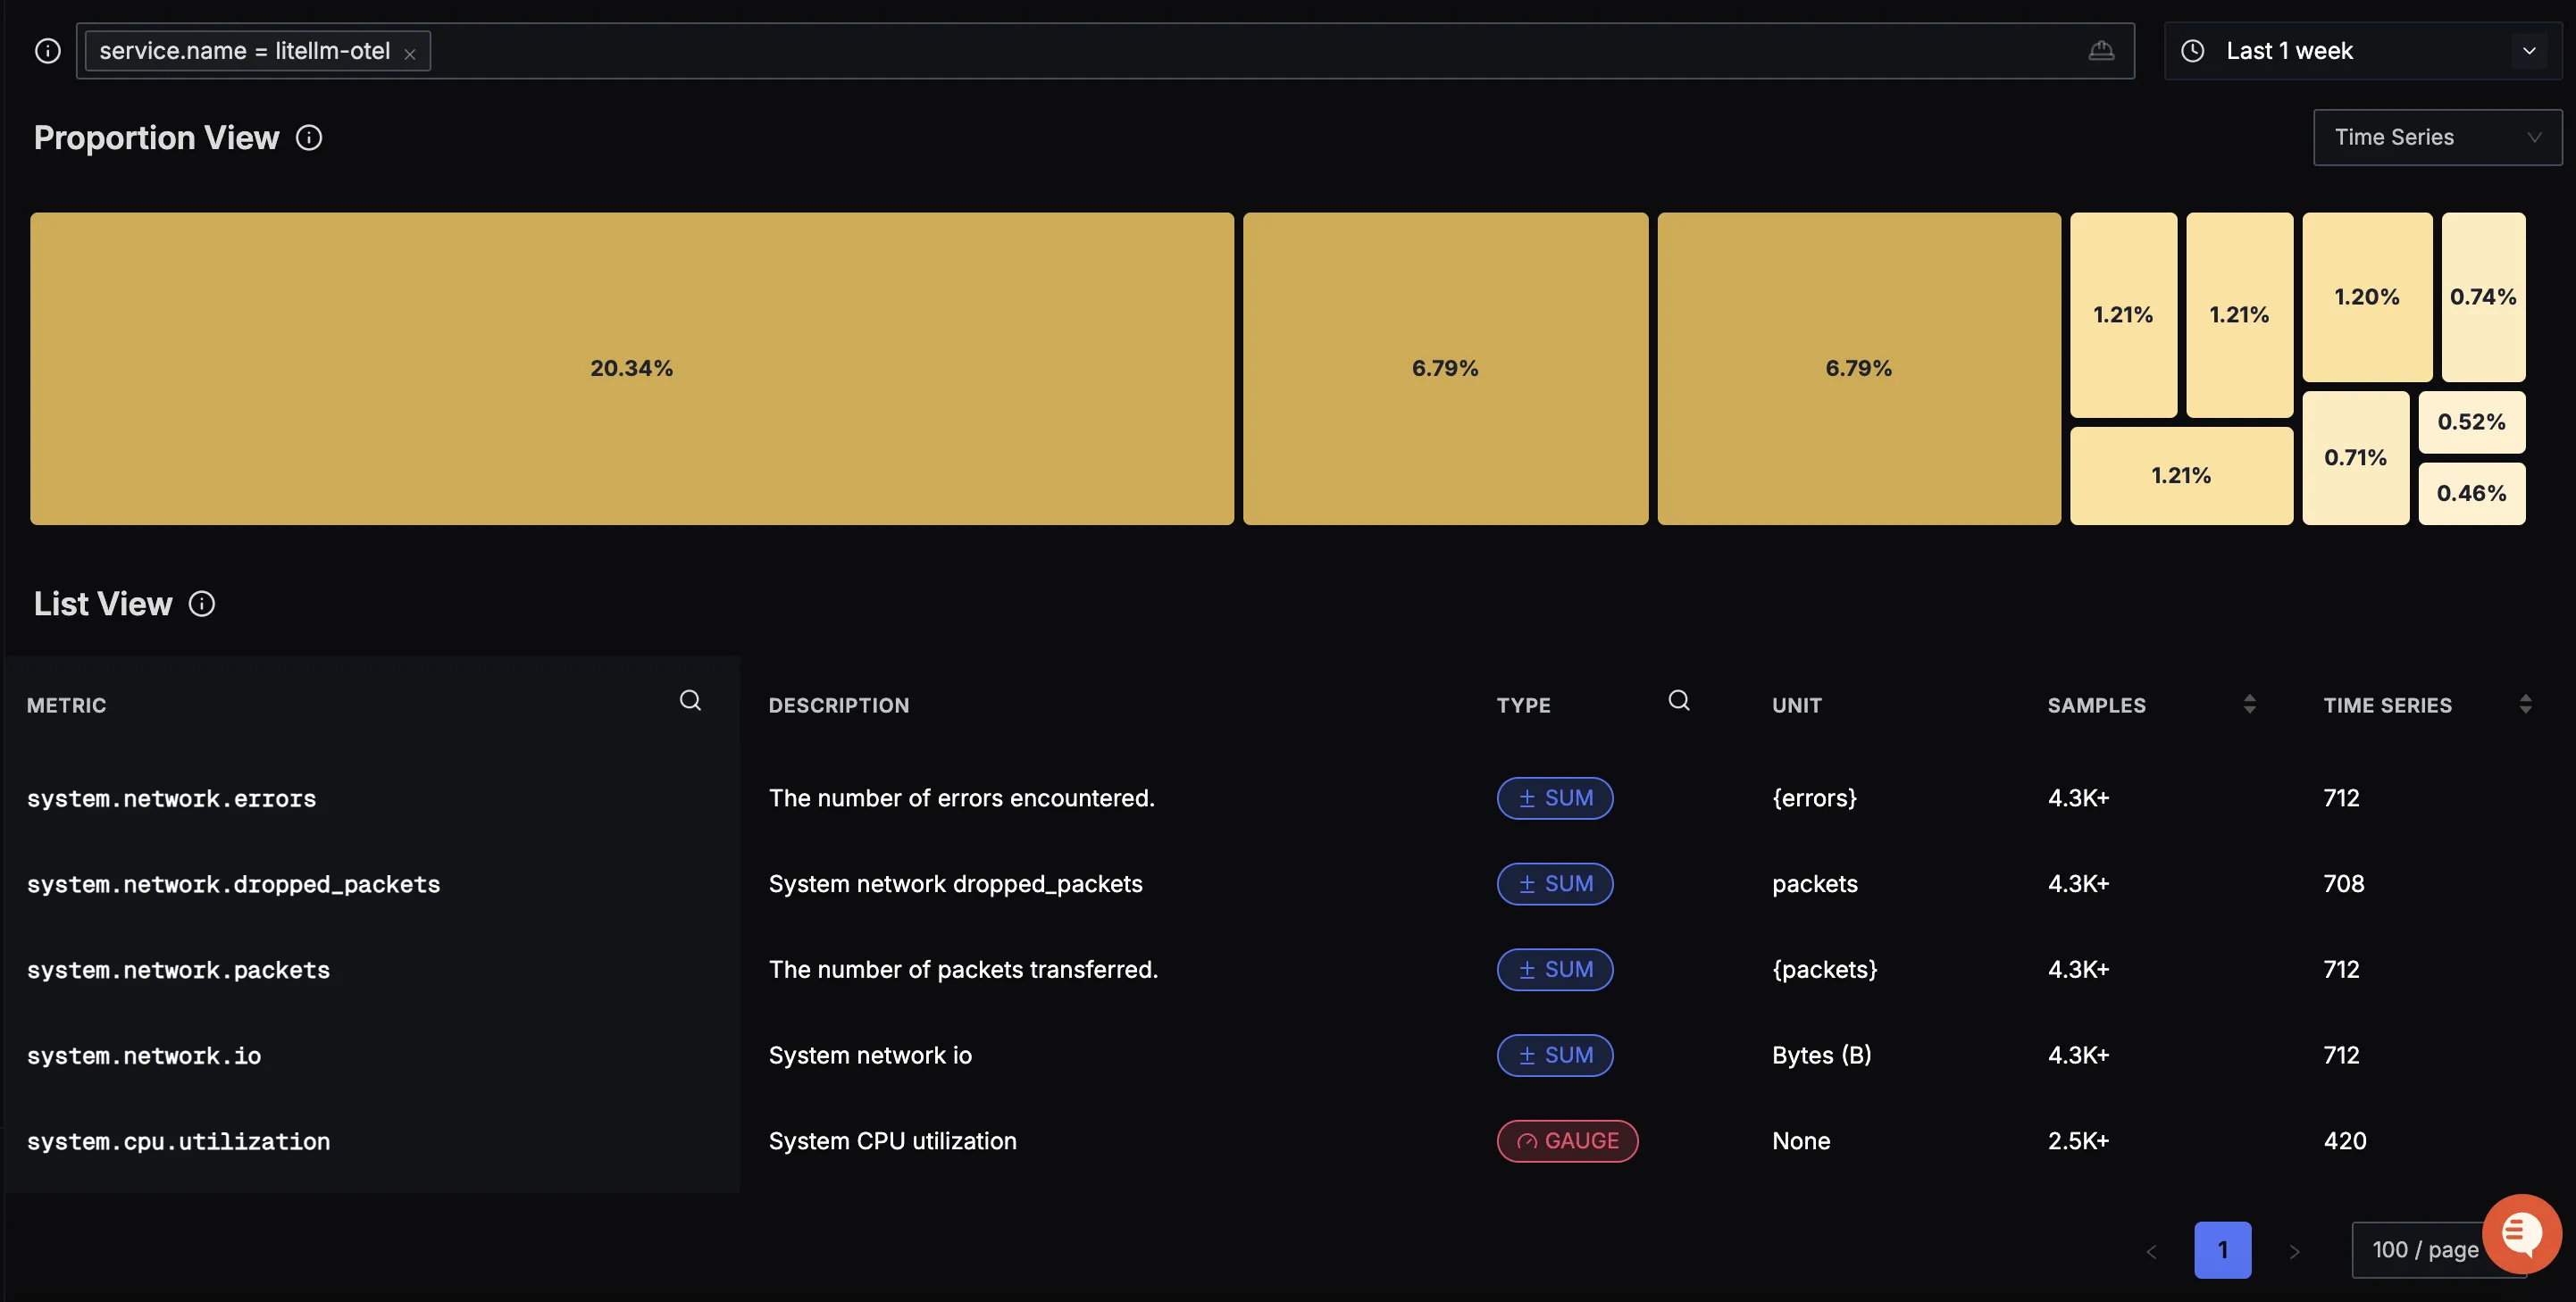
You should be able to see LiteLLM related metrics in Signoz Cloud under the metrics tab:
|
||||
|
||||
|
||||
|
||||
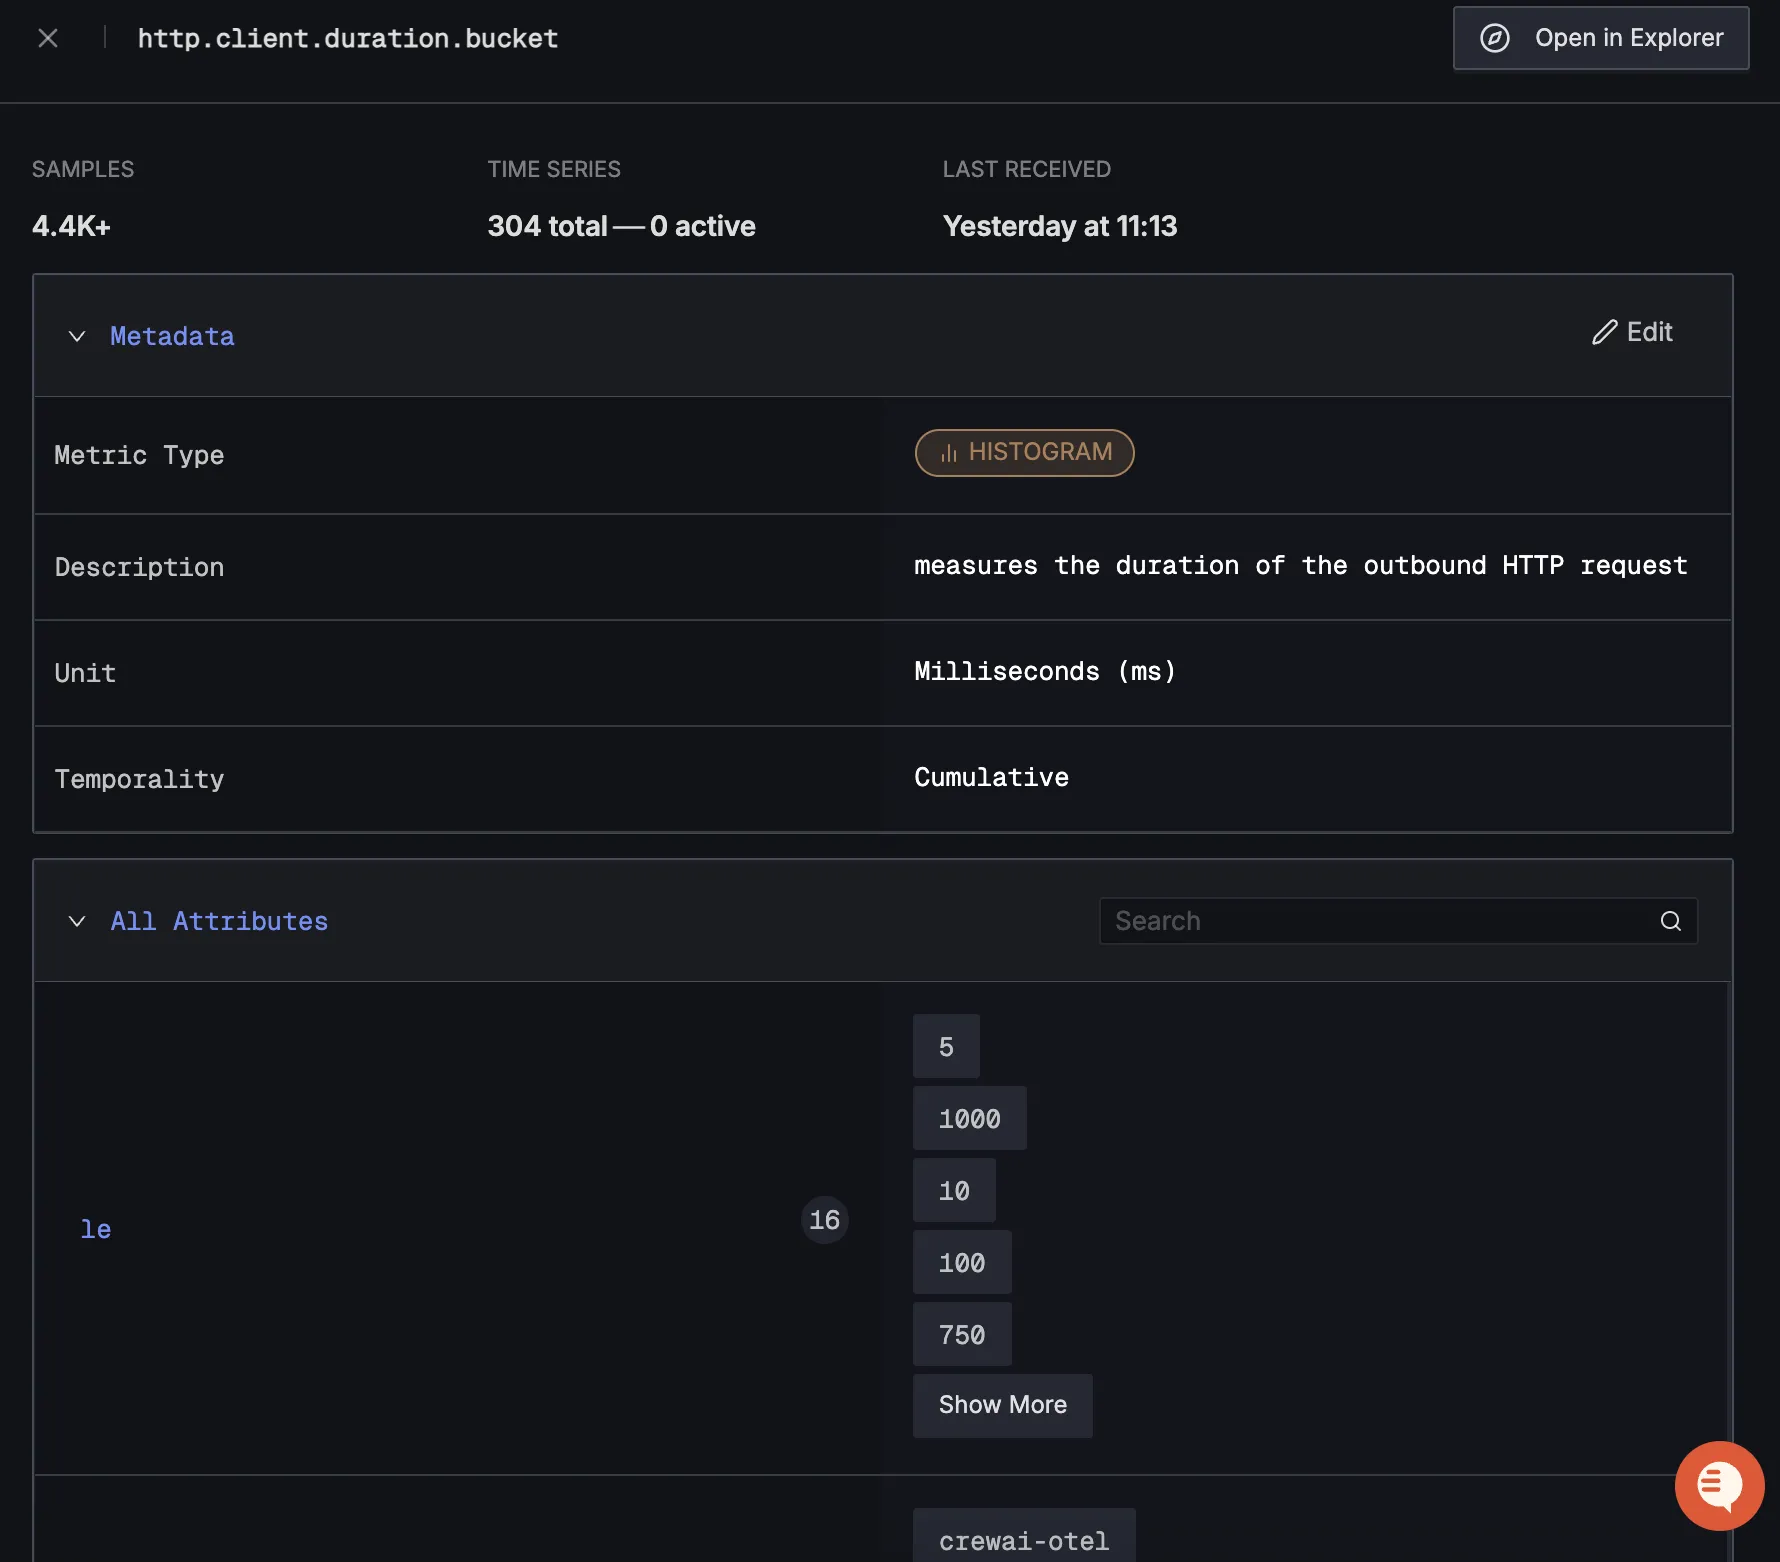
When you click on any of these metrics in SigNoz, you'll see a detailed view of the metric, including attributes:
|
||||
|
||||
|
||||
|
||||
## Dashboard
|
||||
|
||||
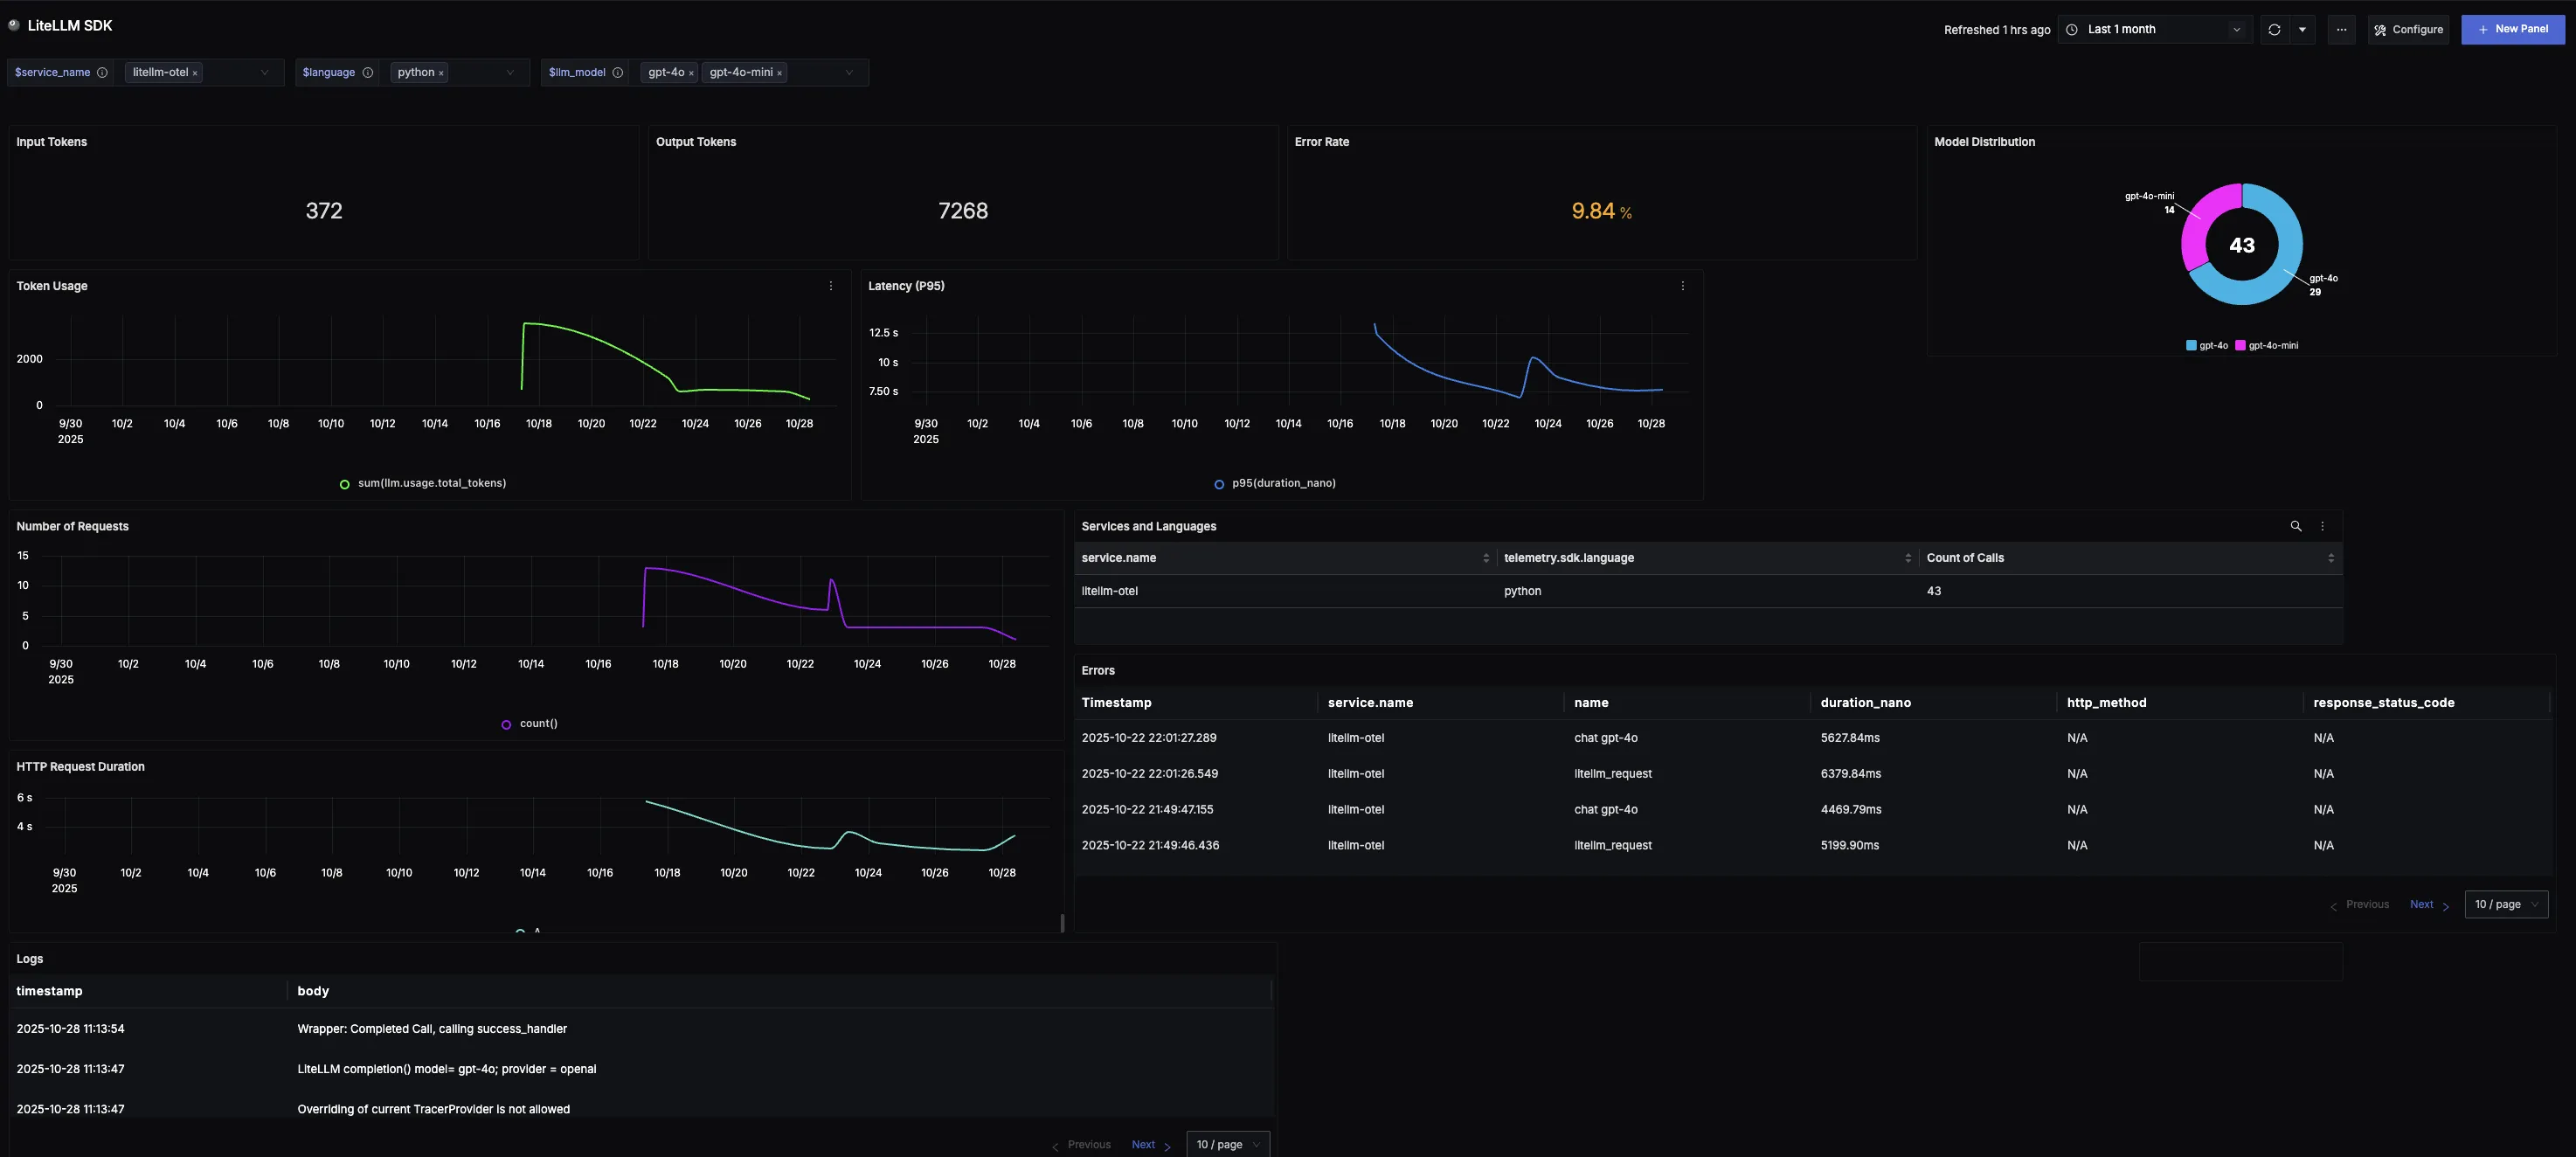
You can also check out our custom LiteLLM SDK dashboard [here](https://signoz.io/docs/dashboards/dashboard-templates/litellm-sdk-dashboard/) which provides specialized visualizations for monitoring your LiteLLM usage in applications. The dashboard includes pre-built charts specifically tailored for LLM usage, along with import instructions to get started quickly.
|
||||
|
||||
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="LiteLLM Proxy Server" label="LiteLLM Proxy Server" default>
|
||||
|
||||
**Step 1:** Install the necessary packages in your Python environment.
|
||||
|
||||
```bash
|
||||
pip install opentelemetry-api \
|
||||
opentelemetry-sdk \
|
||||
opentelemetry-exporter-otlp \
|
||||
'litellm[proxy]'
|
||||
```
|
||||
|
||||
**Step 2:** Configure otel for the LiteLLM Proxy Server
|
||||
|
||||
Add the following to `config.yaml`:
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
callbacks: ['otel']
|
||||
```
|
||||
|
||||
**Step 3:** Set the following environment variables:
|
||||
|
||||
```bash
|
||||
export OTEL_EXPORTER_OTLP_ENDPOINT="https://ingest.<region>.signoz.cloud:443"
|
||||
export OTEL_EXPORTER_OTLP_HEADERS="signoz-ingestion-key=<your_ingestion_key>"
|
||||
export OTEL_EXPORTER_OTLP_PROTOCOL="grpc"
|
||||
export OTEL_TRACES_EXPORTER="otlp"
|
||||
export OTEL_METRICS_EXPORTER="otlp"
|
||||
export OTEL_LOGS_EXPORTER="otlp"
|
||||
```
|
||||
|
||||
- Set the `<region>` to match your SigNoz Cloud [region](https://signoz.io/docs/ingestion/signoz-cloud/overview/#endpoint)
|
||||
- Replace `<your_ingestion_key>` with your SigNoz [ingestion key](https://signoz.io/docs/ingestion/signoz-cloud/keys/)
|
||||
|
||||
> 📌 Note: Using self-hosted SigNoz? Most steps are identical. To adapt this guide, update the endpoint and remove the ingestion key header as shown in [Cloud → Self-Hosted](https://signoz.io/docs/ingestion/cloud-vs-self-hosted/#cloud-to-self-hosted).
|
||||
|
||||
|
||||
**Step 4:** Run the proxy server using the config file:
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
Now any calls made through your LiteLLM proxy server will be traced and sent to SigNoz.
|
||||
|
||||
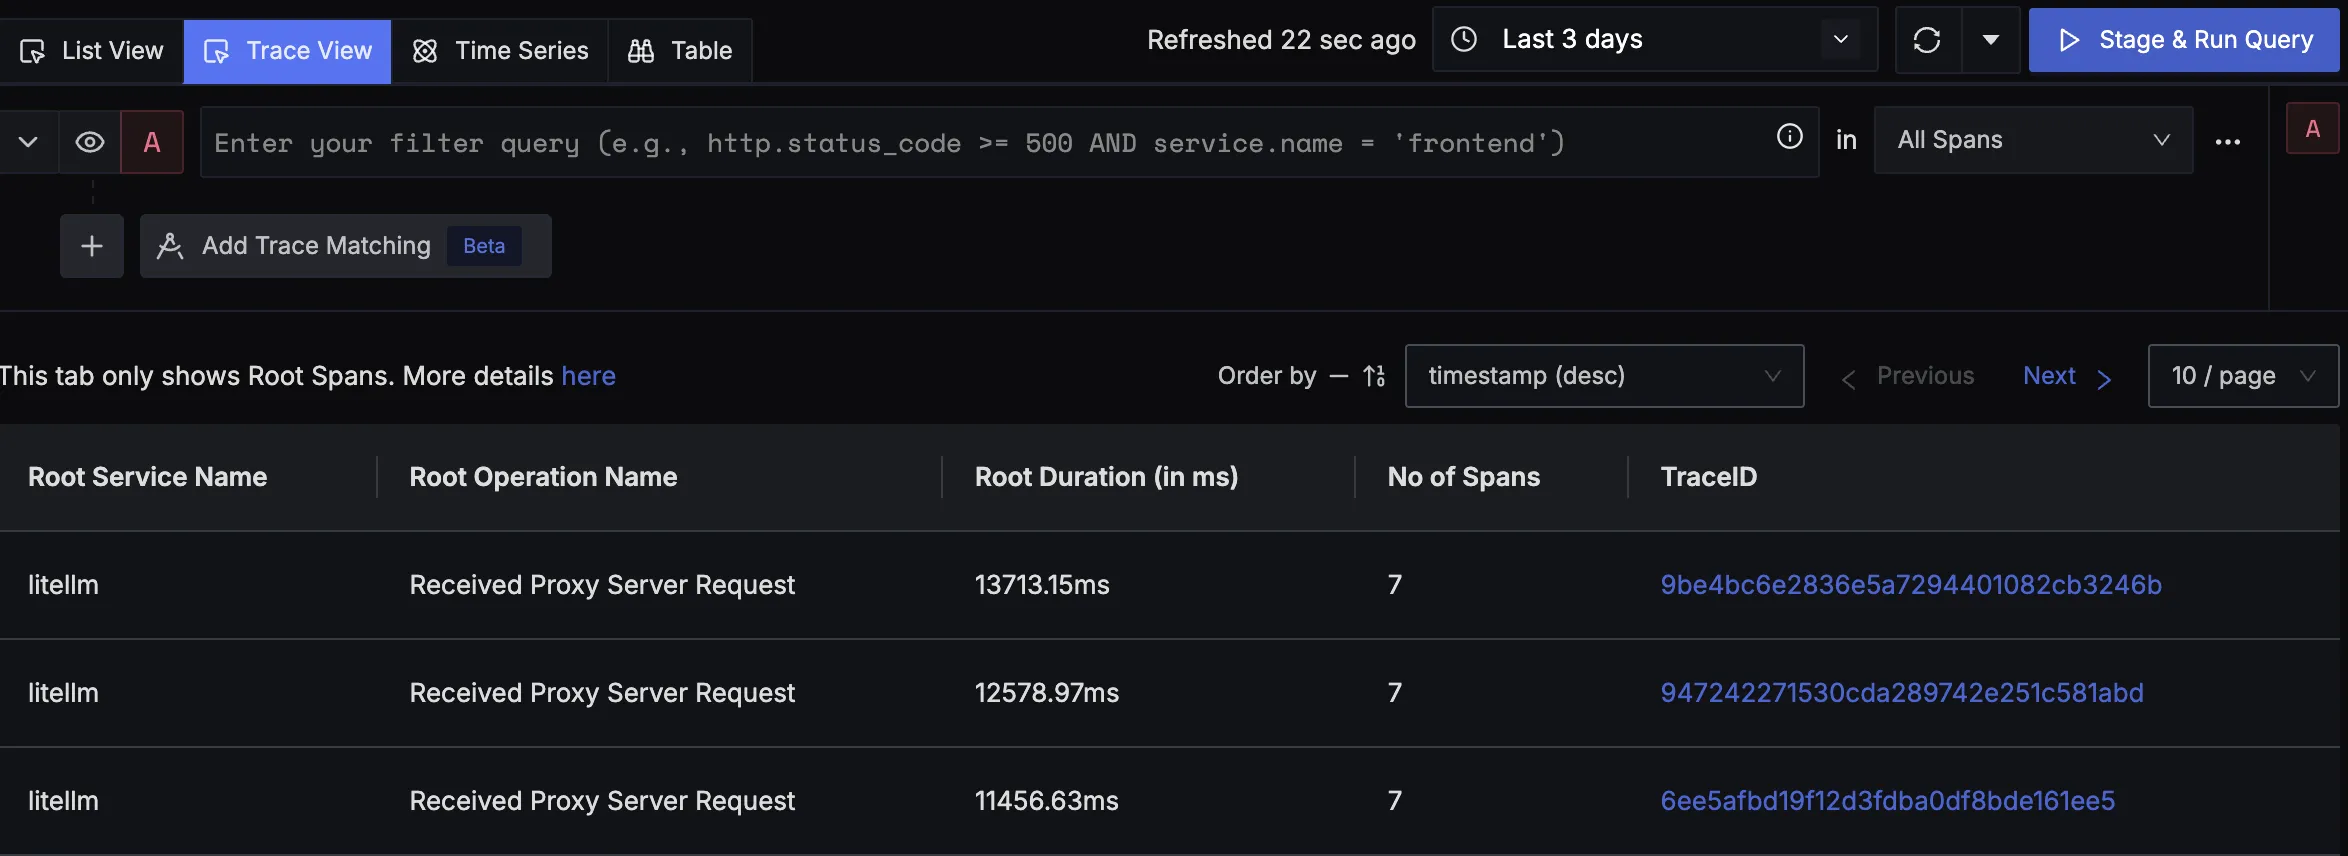
You should be able to view traces in Signoz Cloud under the traces tab:
|
||||
|
||||
|
||||
|
||||
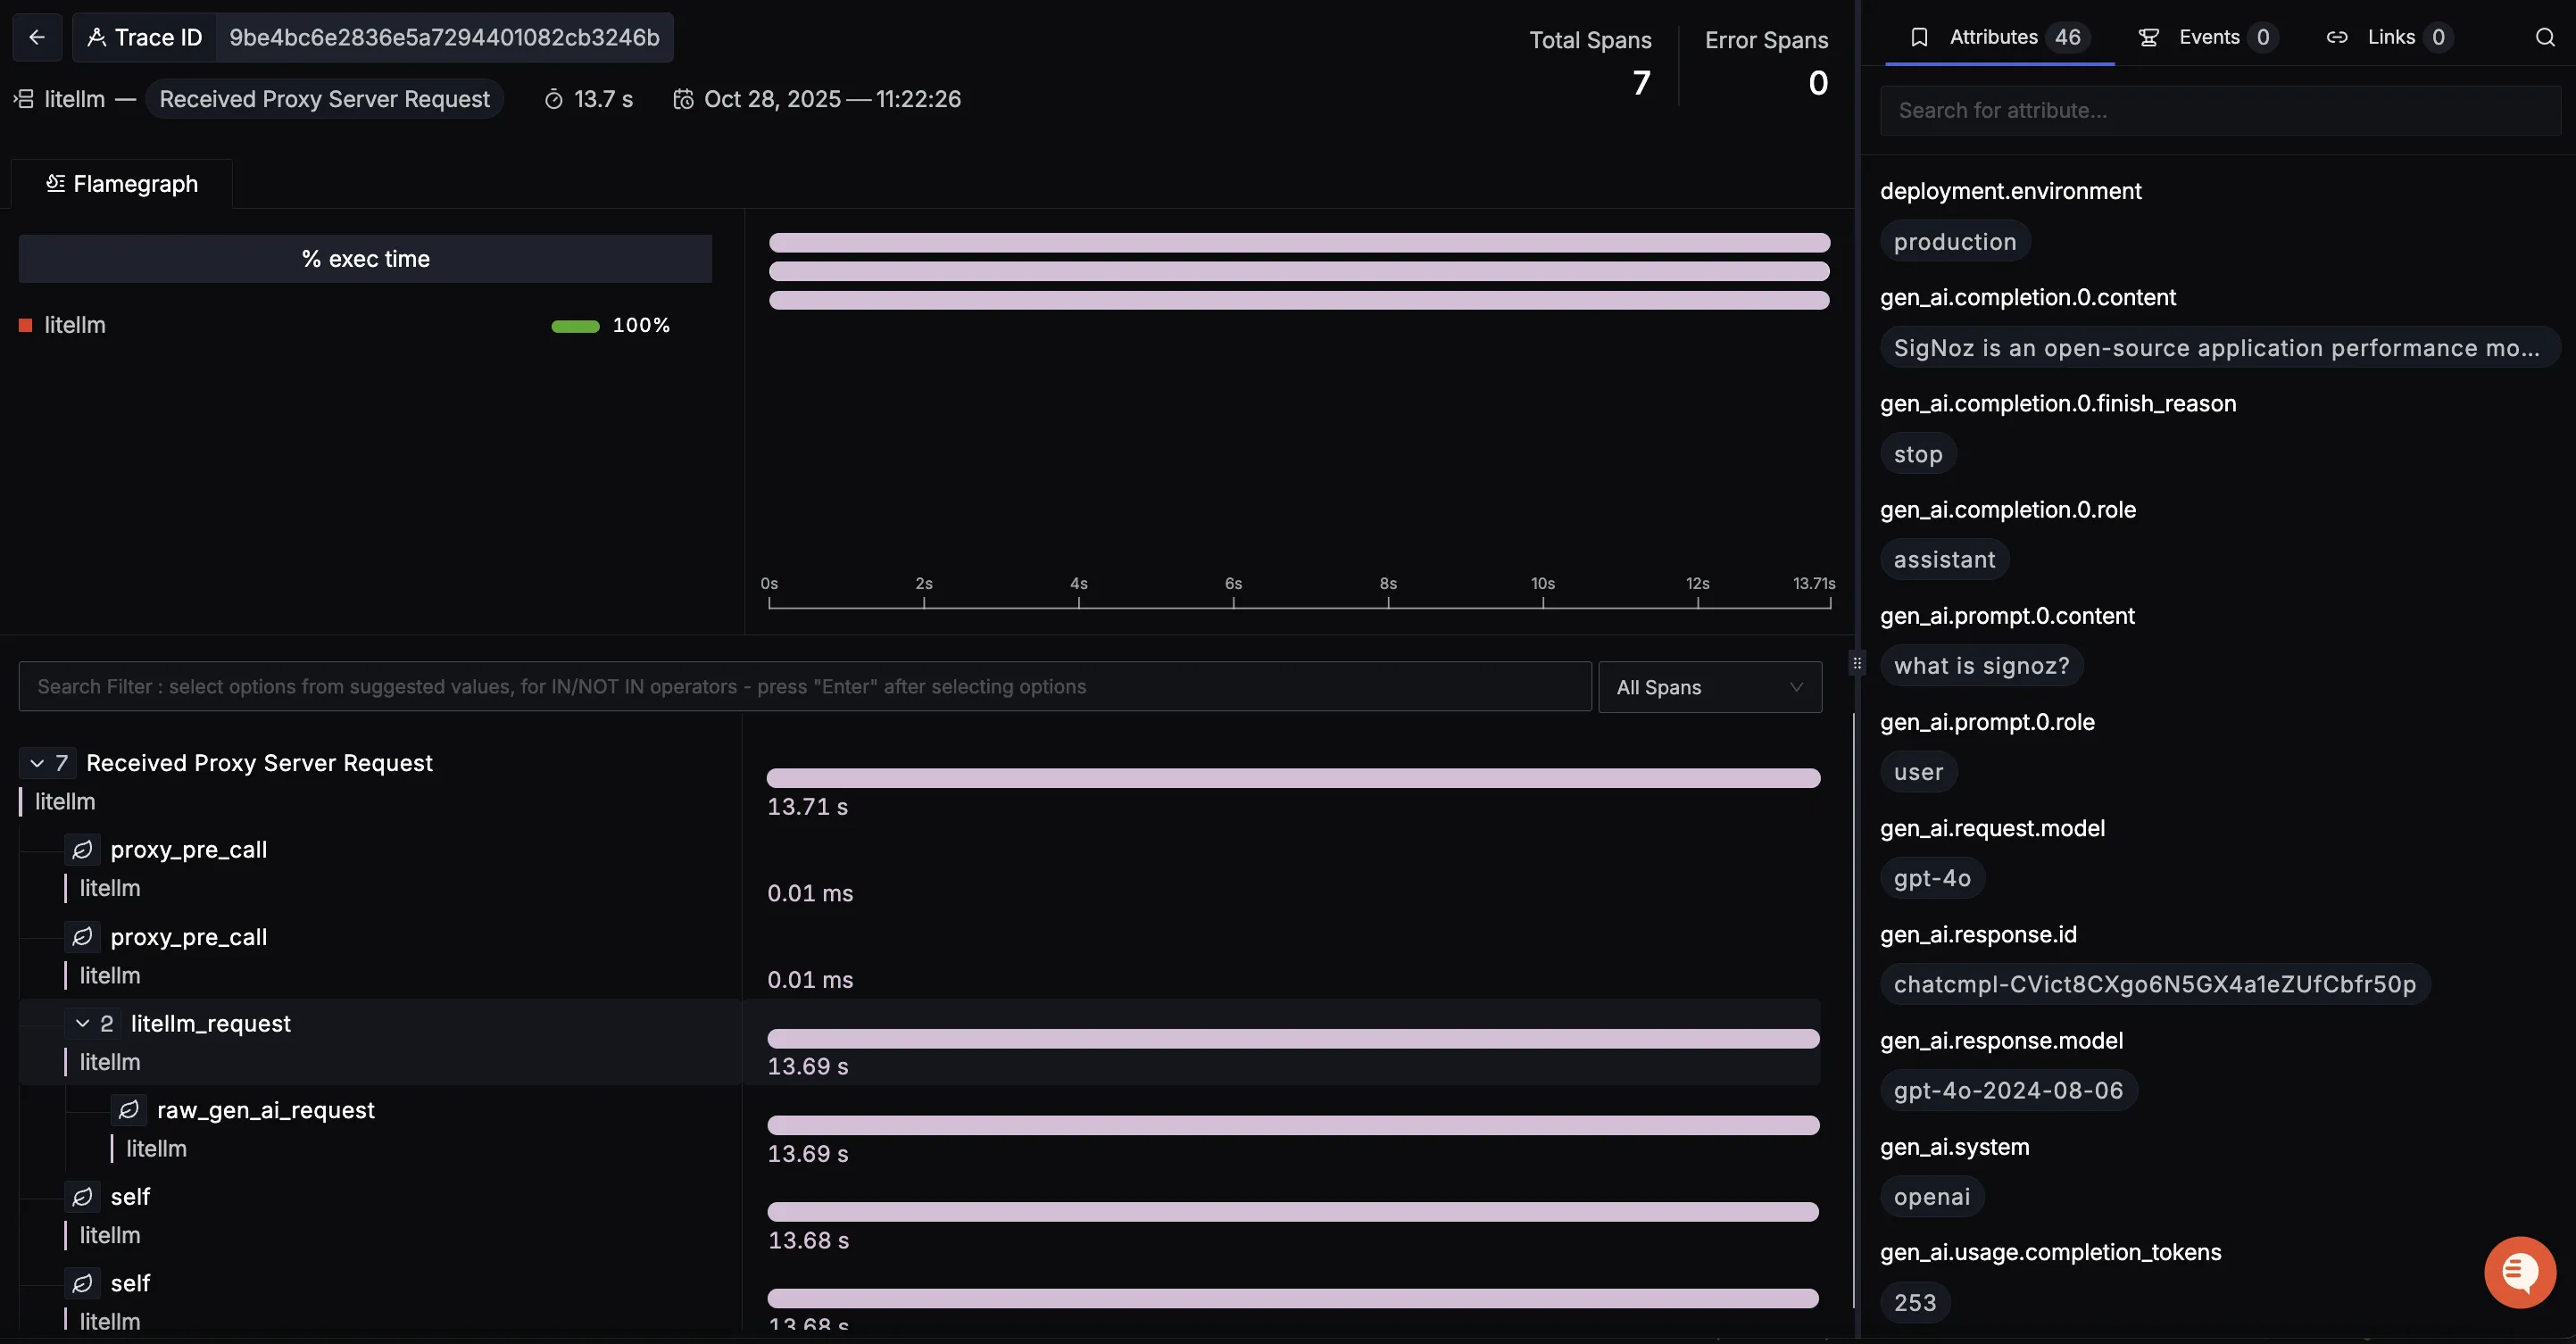
When you click on a trace in SigNoz, you'll see a detailed view of the trace, including all associated spans, along with their events and attributes.
|
||||
|
||||
|
||||
|
||||
## Dashboard
|
||||
|
||||
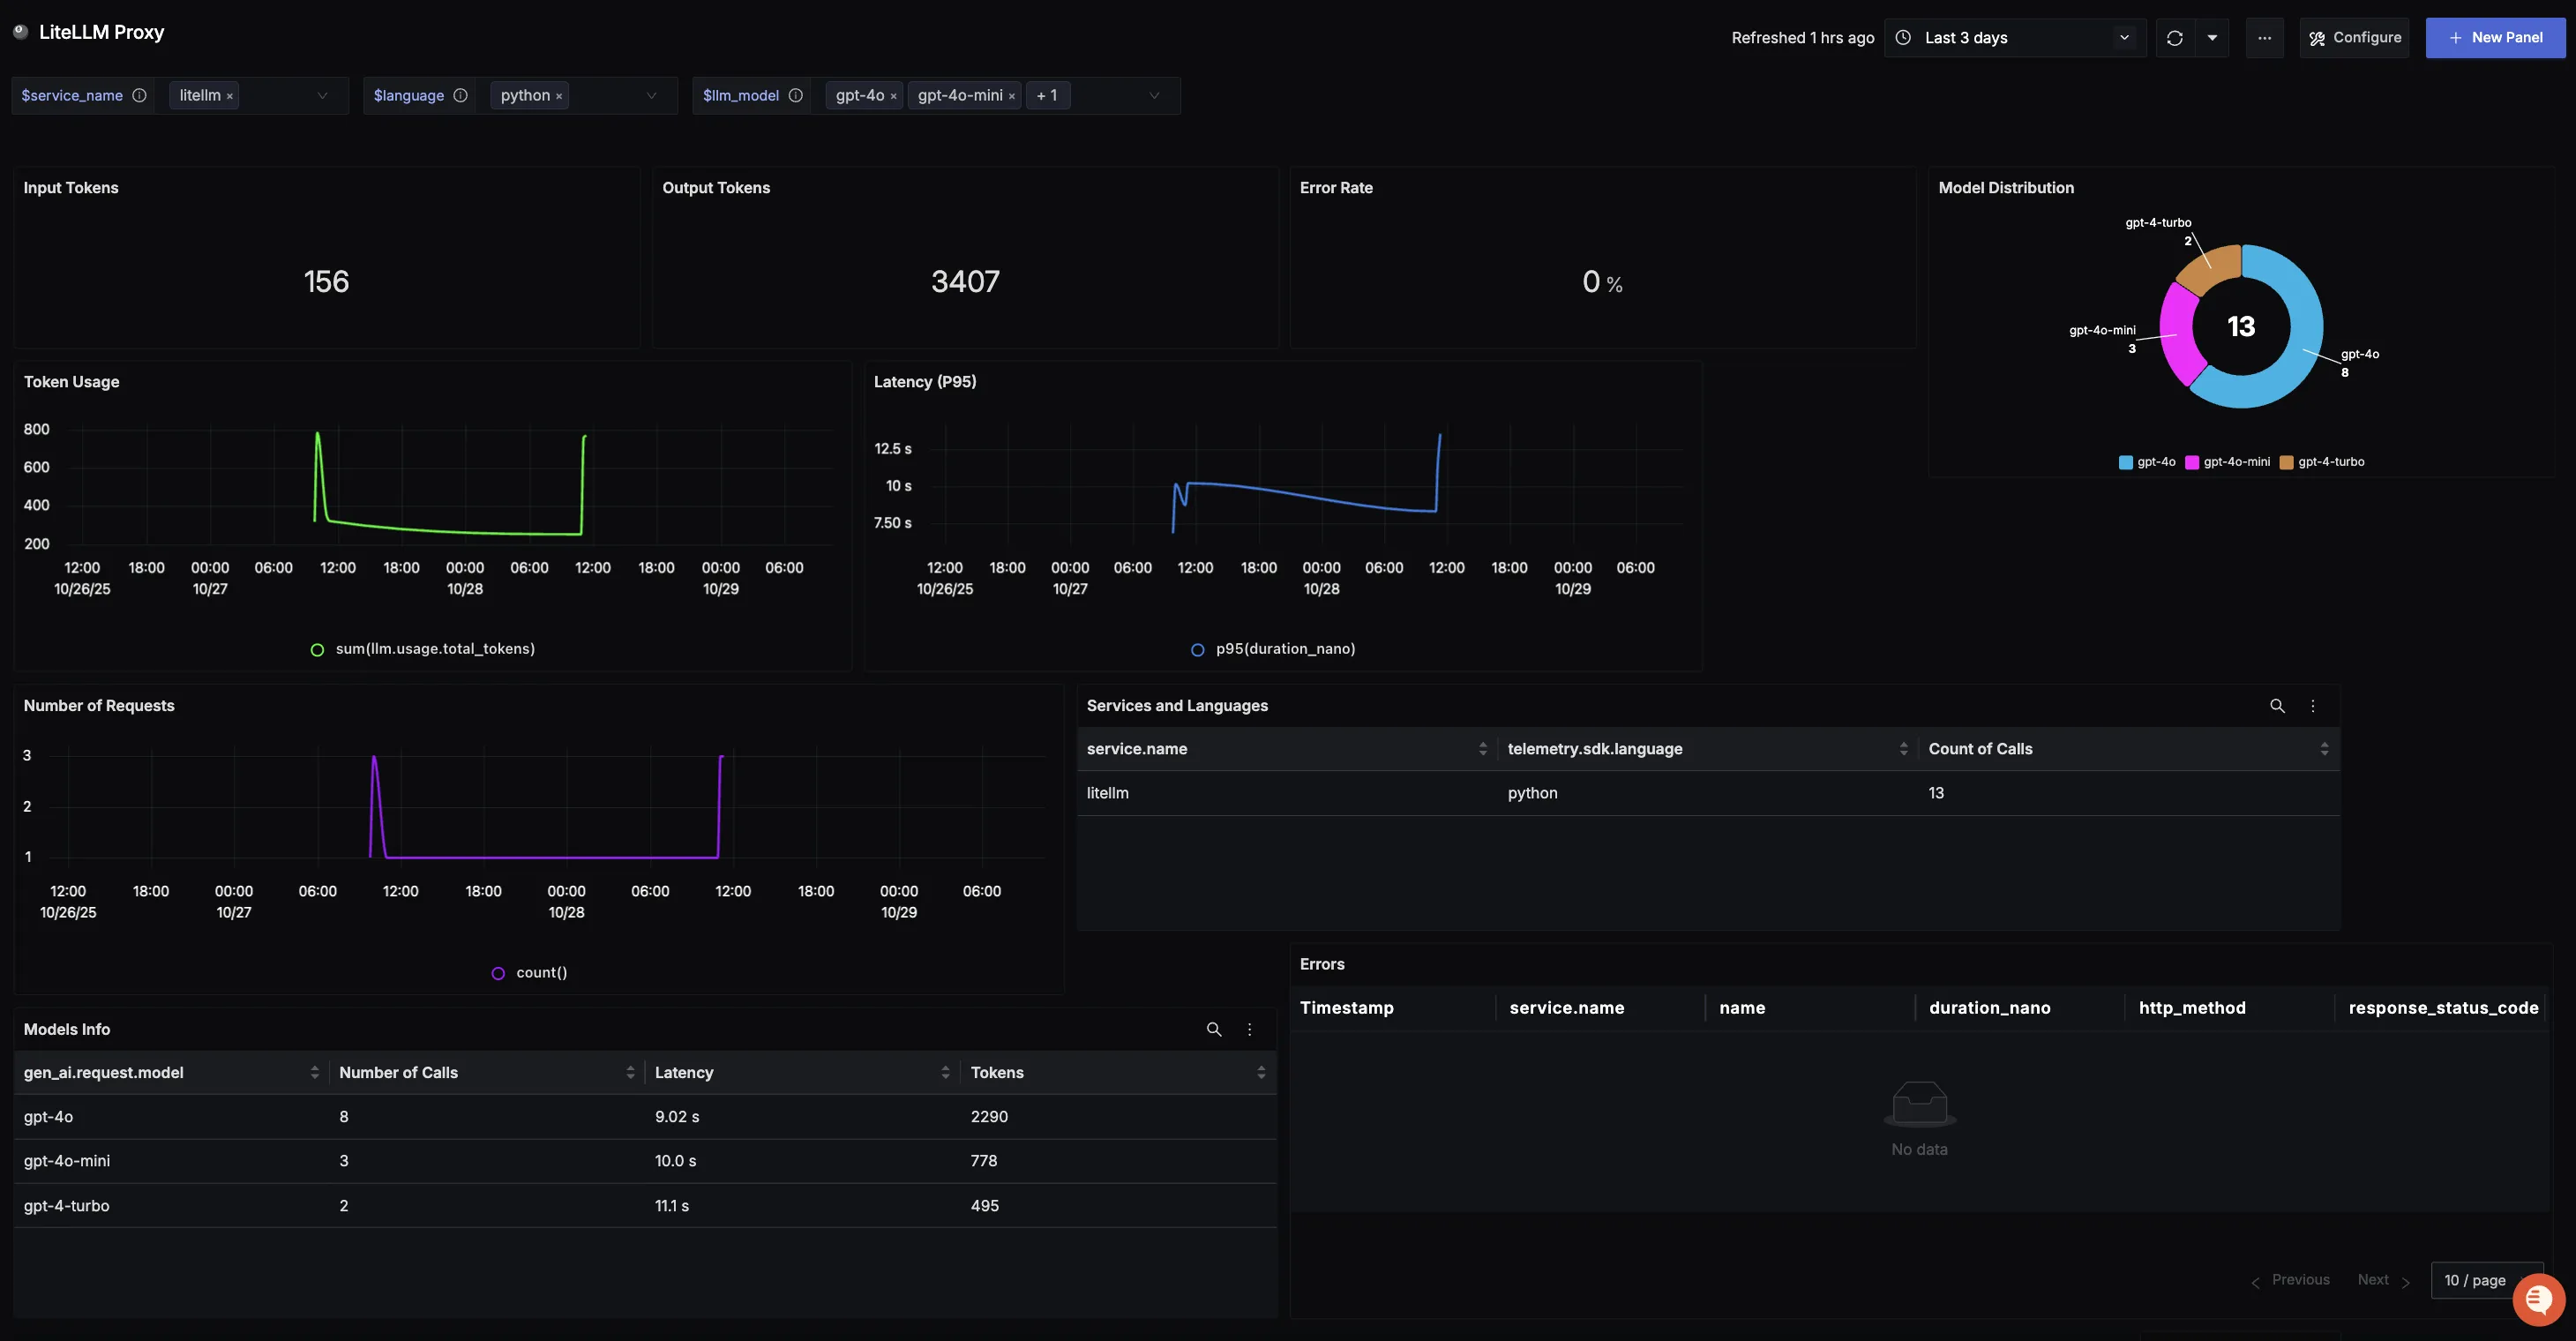
You can also check out our custom LiteLLM Proxy dashboard [here](https://signoz.io/docs/dashboards/dashboard-templates/litellm-proxy-dashboard/) which provides specialized visualizations for monitoring your LiteLLM Proxy usage in applications. The dashboard includes pre-built charts specifically tailored for LLM usage, along with import instructions to get started quickly.
|
||||
|
||||
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
|
@ -11,7 +11,7 @@ from litellm.proxy.auth.user_api_key_auth import user_api_key_auth
|
|||
from litellm.integrations.custom_guardrail import ModifyResponseException
|
||||
from litellm.proxy.common_request_processing import (
|
||||
ProxyBaseLLMRequestProcessing,
|
||||
create_streaming_response,
|
||||
create_response,
|
||||
)
|
||||
from litellm.proxy.common_utils.http_parsing_utils import _read_request_body
|
||||
from litellm.types.utils import TokenCountResponse
|
||||
|
|
@ -106,7 +106,7 @@ async def anthropic_response( # noqa: PLR0915
|
|||
)
|
||||
)
|
||||
|
||||
return await create_streaming_response(
|
||||
return await create_response(
|
||||
generator=selected_data_generator,
|
||||
media_type="text/event-stream",
|
||||
headers={},
|
||||
|
|
|
|||
|
|
@ -17,7 +17,7 @@ from typing import (
|
|||
import httpx
|
||||
import orjson
|
||||
from fastapi import HTTPException, Request, status
|
||||
from fastapi.responses import Response, StreamingResponse
|
||||
from fastapi.responses import JSONResponse, Response, StreamingResponse
|
||||
|
||||
import litellm
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
|
|
@ -96,16 +96,55 @@ async def _parse_event_data_for_error(event_line: Union[str, bytes]) -> Optional
|
|||
return None
|
||||
|
||||
|
||||
async def create_streaming_response(
|
||||
def _extract_error_from_sse_chunk(event_line: Union[str, bytes]) -> dict:
|
||||
"""
|
||||
Extract error dictionary from SSE format chunk.
|
||||
|
||||
Args:
|
||||
event_line: SSE format event line, e.g. "data: {"error": {...}}\n\n"
|
||||
|
||||
Returns:
|
||||
Error dictionary in OpenAI API format
|
||||
"""
|
||||
event_line = (
|
||||
event_line.decode("utf-8") if isinstance(event_line, bytes) else event_line
|
||||
)
|
||||
|
||||
# Default error format
|
||||
default_error = {
|
||||
"message": "Unknown error",
|
||||
"type": "internal_server_error",
|
||||
"param": None,
|
||||
"code": "500",
|
||||
}
|
||||
|
||||
if event_line.startswith("data: "):
|
||||
json_str = event_line[len("data: ") :].strip()
|
||||
if not json_str or json_str == "[DONE]":
|
||||
return default_error
|
||||
|
||||
try:
|
||||
data = orjson.loads(json_str)
|
||||
if isinstance(data, dict) and "error" in data:
|
||||
error_obj = data["error"]
|
||||
if isinstance(error_obj, dict):
|
||||
return error_obj
|
||||
except (orjson.JSONDecodeError, json.JSONDecodeError):
|
||||
pass
|
||||
|
||||
return default_error
|
||||
|
||||
|
||||
async def create_response(
|
||||
generator: AsyncGenerator[str, None],
|
||||
media_type: str,
|
||||
headers: dict,
|
||||
default_status_code: int = status.HTTP_200_OK,
|
||||
) -> StreamingResponse:
|
||||
) -> Union[StreamingResponse, JSONResponse]:
|
||||
"""
|
||||
Creates a StreamingResponse by inspecting the first chunk for an error code.
|
||||
The entire original generator content is streamed, but the HTTP status code
|
||||
of the response is set based on the first chunk if it's a recognized error.
|
||||
Create streaming response, checking if the first chunk is an error.
|
||||
If the first chunk is an error, return a standard JSON error response.
|
||||
Otherwise, return StreamingResponse and stream all content.
|
||||
"""
|
||||
first_chunk_value: Optional[str] = None
|
||||
final_status_code = default_status_code
|
||||
|
|
@ -124,9 +163,27 @@ async def create_streaming_response(
|
|||
first_chunk_value
|
||||
)
|
||||
if error_code_from_chunk is not None:
|
||||
# First chunk is an error, stream hasn't really started yet
|
||||
# Should return standard JSON error response instead of SSE format
|
||||
final_status_code = error_code_from_chunk
|
||||
verbose_proxy_logger.debug(
|
||||
f"Error detected in first stream chunk. Status code set to: {final_status_code}"
|
||||
f"Error detected in first stream chunk. Returning JSON error response with status code: {final_status_code}"
|
||||
)
|
||||
|
||||
# Parse error content
|
||||
error_dict = _extract_error_from_sse_chunk(first_chunk_value)
|
||||
|
||||
# Consume and close generator (avoid resource leak)
|
||||
try:
|
||||
await generator.aclose()
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
# Return JSON format error response
|
||||
return JSONResponse(
|
||||
status_code=final_status_code,
|
||||
content={"error": error_dict},
|
||||
headers=headers,
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.debug(f"Error parsing first chunk value: {e}")
|
||||
|
|
@ -647,7 +704,7 @@ class ProxyBaseLLMRequestProcessing:
|
|||
proxy_logging_obj=proxy_logging_obj,
|
||||
)
|
||||
)
|
||||
return await create_streaming_response(
|
||||
return await create_response(
|
||||
generator=selected_data_generator,
|
||||
media_type="text/event-stream",
|
||||
headers=custom_headers,
|
||||
|
|
@ -658,7 +715,7 @@ class ProxyBaseLLMRequestProcessing:
|
|||
user_api_key_dict=user_api_key_dict,
|
||||
request_data=self.data,
|
||||
)
|
||||
return await create_streaming_response(
|
||||
return await create_response(
|
||||
generator=selected_data_generator,
|
||||
media_type="text/event-stream",
|
||||
headers=custom_headers,
|
||||
|
|
|
|||
|
|
@ -229,7 +229,7 @@ from litellm.proxy.batches_endpoints.endpoints import router as batches_router
|
|||
from litellm.proxy.caching_routes import router as caching_router
|
||||
from litellm.proxy.common_request_processing import (
|
||||
ProxyBaseLLMRequestProcessing,
|
||||
create_streaming_response,
|
||||
create_response,
|
||||
)
|
||||
from litellm.proxy.common_utils.callback_utils import initialize_callbacks_on_proxy
|
||||
from litellm.proxy.common_utils.debug_utils import init_verbose_loggers
|
||||
|
|
@ -6736,7 +6736,7 @@ async def run_thread(
|
|||
if (
|
||||
"stream" in data and data["stream"] is True
|
||||
): # use generate_responses to stream responses
|
||||
return await create_streaming_response(
|
||||
return await create_response(
|
||||
generator=async_assistants_data_generator(
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
response=response,
|
||||
|
|
|
|||
|
|
@ -3,7 +3,7 @@ from unittest.mock import AsyncMock, MagicMock
|
|||
|
||||
import pytest
|
||||
from fastapi import Request, status
|
||||
from fastapi.responses import StreamingResponse
|
||||
from fastapi.responses import JSONResponse, StreamingResponse
|
||||
|
||||
import litellm
|
||||
from litellm._uuid import uuid
|
||||
|
|
@ -11,9 +11,10 @@ from litellm.integrations.opentelemetry import UserAPIKeyAuth
|
|||
from litellm.proxy.common_request_processing import (
|
||||
ProxyBaseLLMRequestProcessing,
|
||||
ProxyConfig,
|
||||
_extract_error_from_sse_chunk,
|
||||
_get_cost_breakdown_from_logging_obj,
|
||||
_parse_event_data_for_error,
|
||||
create_streaming_response,
|
||||
create_response,
|
||||
)
|
||||
from litellm.proxy.utils import ProxyLogging
|
||||
|
||||
|
|
@ -602,21 +603,27 @@ class TestCommonRequestProcessingHelpers:
|
|||
assert await _parse_event_data_for_error(event_line) == expected_code
|
||||
|
||||
async def test_create_streaming_response_first_chunk_is_error(self):
|
||||
"""
|
||||
Test that when the first chunk is an error, a JSON error response is returned
|
||||
instead of an SSE streaming response
|
||||
"""
|
||||
async def mock_generator():
|
||||
yield 'data: {"error": {"code": 403, "message": "forbidden"}}\n\n'
|
||||
yield 'data: {"content": "more data"}\n\n'
|
||||
yield "data: [DONE]\n\n"
|
||||
|
||||
response = await create_streaming_response(
|
||||
response = await create_response(
|
||||
mock_generator(), "text/event-stream", {}
|
||||
)
|
||||
# Should return JSONResponse instead of StreamingResponse
|
||||
assert isinstance(response, JSONResponse)
|
||||
assert response.status_code == status.HTTP_403_FORBIDDEN
|
||||
content = await self.consume_stream(response)
|
||||
assert content == [
|
||||
'data: {"error": {"code": 403, "message": "forbidden"}}\n\n',
|
||||
'data: {"content": "more data"}\n\n',
|
||||
"data: [DONE]\n\n",
|
||||
]
|
||||
# Verify the response is in standard JSON error format
|
||||
import json
|
||||
body = json.loads(response.body.decode())
|
||||
assert "error" in body
|
||||
assert body["error"]["code"] == 403
|
||||
assert body["error"]["message"] == "forbidden"
|
||||
|
||||
async def test_create_streaming_response_first_chunk_not_error(self):
|
||||
async def mock_generator():
|
||||
|
|
@ -624,7 +631,7 @@ class TestCommonRequestProcessingHelpers:
|
|||
yield 'data: {"content": "second part"}\n\n'
|
||||
yield "data: [DONE]\n\n"
|
||||
|
||||
response = await create_streaming_response(
|
||||
response = await create_response(
|
||||
mock_generator(), "text/event-stream", {}
|
||||
)
|
||||
assert response.status_code == status.HTTP_200_OK
|
||||
|
|
@ -641,7 +648,7 @@ class TestCommonRequestProcessingHelpers:
|
|||
yield
|
||||
# Implicitly raises StopAsyncIteration
|
||||
|
||||
response = await create_streaming_response(
|
||||
response = await create_response(
|
||||
mock_generator(), "text/event-stream", {}
|
||||
)
|
||||
assert response.status_code == status.HTTP_200_OK
|
||||
|
|
@ -654,7 +661,7 @@ class TestCommonRequestProcessingHelpers:
|
|||
mock_gen = AsyncMock()
|
||||
mock_gen.__anext__.side_effect = StopAsyncIteration
|
||||
|
||||
response = await create_streaming_response(mock_gen, "text/event-stream", {})
|
||||
response = await create_response(mock_gen, "text/event-stream", {})
|
||||
assert response.status_code == status.HTTP_200_OK
|
||||
content = await self.consume_stream(response)
|
||||
assert content == []
|
||||
|
|
@ -665,7 +672,7 @@ class TestCommonRequestProcessingHelpers:
|
|||
mock_gen = AsyncMock()
|
||||
mock_gen.__anext__.side_effect = ValueError("Test error from generator")
|
||||
|
||||
response = await create_streaming_response(mock_gen, "text/event-stream", {})
|
||||
response = await create_response(mock_gen, "text/event-stream", {})
|
||||
assert response.status_code == status.HTTP_500_INTERNAL_SERVER_ERROR
|
||||
content = await self.consume_stream(response)
|
||||
expected_error_data = {
|
||||
|
|
@ -682,19 +689,24 @@ class TestCommonRequestProcessingHelpers:
|
|||
assert content[1] == "data: [DONE]\n\n"
|
||||
|
||||
async def test_create_streaming_response_first_chunk_error_string_code(self):
|
||||
"""
|
||||
Test that when the first chunk contains a string error code, a JSON error response is returned
|
||||
"""
|
||||
async def mock_generator():
|
||||
yield 'data: {"error": {"code": "429", "message": "too many requests"}}\n\n'
|
||||
yield "data: [DONE]\n\n"
|
||||
|
||||
response = await create_streaming_response(
|
||||
response = await create_response(
|
||||
mock_generator(), "text/event-stream", {}
|
||||
)
|
||||
assert isinstance(response, JSONResponse)
|
||||
assert response.status_code == status.HTTP_429_TOO_MANY_REQUESTS
|
||||
content = await self.consume_stream(response)
|
||||
assert content == [
|
||||
'data: {"error": {"code": "429", "message": "too many requests"}}\n\n',
|
||||
"data: [DONE]\n\n",
|
||||
]
|
||||
# Verify the response is in standard JSON error format
|
||||
import json
|
||||
body = json.loads(response.body.decode())
|
||||
assert "error" in body
|
||||
assert body["error"]["code"] == "429"
|
||||
assert body["error"]["message"] == "too many requests"
|
||||
|
||||
async def test_create_streaming_response_custom_headers(self):
|
||||
async def mock_generator():
|
||||
|
|
@ -702,7 +714,7 @@ class TestCommonRequestProcessingHelpers:
|
|||
yield "data: [DONE]\n\n"
|
||||
|
||||
custom_headers = {"X-Custom-Header": "TestValue"}
|
||||
response = await create_streaming_response(
|
||||
response = await create_response(
|
||||
mock_generator(), "text/event-stream", custom_headers
|
||||
)
|
||||
assert response.headers["x-custom-header"] == "TestValue"
|
||||
|
|
@ -712,7 +724,7 @@ class TestCommonRequestProcessingHelpers:
|
|||
yield 'data: {"content": "data"}\n\n'
|
||||
yield "data: [DONE]\n\n"
|
||||
|
||||
response = await create_streaming_response(
|
||||
response = await create_response(
|
||||
mock_generator(),
|
||||
"text/event-stream",
|
||||
{},
|
||||
|
|
@ -729,7 +741,7 @@ class TestCommonRequestProcessingHelpers:
|
|||
async def mock_generator():
|
||||
yield "data: [DONE]\n\n"
|
||||
|
||||
response = await create_streaming_response(
|
||||
response = await create_response(
|
||||
mock_generator(), "text/event-stream", {}
|
||||
)
|
||||
assert response.status_code == status.HTTP_200_OK # Default status
|
||||
|
|
@ -742,7 +754,7 @@ class TestCommonRequestProcessingHelpers:
|
|||
yield 'data: {"content": "actual data"}\n\n'
|
||||
yield "data: [DONE]\n\n"
|
||||
|
||||
response = await create_streaming_response(
|
||||
response = await create_response(
|
||||
mock_generator(), "text/event-stream", {}
|
||||
)
|
||||
assert response.status_code == status.HTTP_200_OK # Default status
|
||||
|
|
@ -773,7 +785,7 @@ class TestCommonRequestProcessingHelpers:
|
|||
|
||||
# Patch the tracer in the common_request_processing module
|
||||
with patch("litellm.proxy.common_request_processing.tracer", mock_tracer):
|
||||
response = await create_streaming_response(
|
||||
response = await create_response(
|
||||
mock_generator(), "text/event-stream", {}
|
||||
)
|
||||
|
||||
|
|
@ -810,7 +822,10 @@ class TestCommonRequestProcessingHelpers:
|
|||
), f"Call {i} should have operation name 'streaming.chunk.yield', got {args[0]}"
|
||||
|
||||
async def test_create_streaming_response_dd_trace_with_error_chunk(self):
|
||||
"""Test that dd trace is applied even when the first chunk contains an error"""
|
||||
"""
|
||||
Test that when the first chunk contains an error, JSONResponse is returned
|
||||
and tracing is not triggered (since it's not a streaming response)
|
||||
"""
|
||||
from unittest.mock import patch
|
||||
|
||||
# Create a mock tracer
|
||||
|
|
@ -827,28 +842,107 @@ class TestCommonRequestProcessingHelpers:
|
|||
|
||||
# Patch the tracer in the common_request_processing module
|
||||
with patch("litellm.proxy.common_request_processing.tracer", mock_tracer):
|
||||
response = await create_streaming_response(
|
||||
response = await create_response(
|
||||
mock_generator(), "text/event-stream", {}
|
||||
)
|
||||
|
||||
# Even with error, status should be set to error code but tracing should still work
|
||||
# Should return JSONResponse instead of StreamingResponse
|
||||
assert isinstance(response, JSONResponse)
|
||||
assert response.status_code == 400
|
||||
|
||||
# Consume the stream to trigger the tracer calls
|
||||
content = await self.consume_stream(response)
|
||||
# Verify the response is in standard JSON error format
|
||||
import json
|
||||
body = json.loads(response.body.decode())
|
||||
assert "error" in body
|
||||
assert body["error"]["code"] == 400
|
||||
assert body["error"]["message"] == "bad request"
|
||||
|
||||
# Verify all chunks are present
|
||||
assert len(content) == 3
|
||||
# Since JSONResponse is returned instead of StreamingResponse, streaming tracing should not be triggered
|
||||
# tracer.trace should not be called
|
||||
assert mock_tracer.trace.call_count == 0
|
||||
|
||||
# Verify that tracer.trace was called for each chunk
|
||||
assert mock_tracer.trace.call_count == 3
|
||||
|
||||
# Verify that each call was made with the correct operation name
|
||||
actual_calls = mock_tracer.trace.call_args_list
|
||||
assert len(actual_calls) == 3
|
||||
class TestExtractErrorFromSSEChunk:
|
||||
"""Tests for _extract_error_from_sse_chunk function"""
|
||||
|
||||
def test_extract_error_from_sse_chunk_with_valid_error(self):
|
||||
"""Test extracting error information from a standard SSE chunk"""
|
||||
chunk = 'data: {"error": {"code": 403, "message": "forbidden", "type": "auth_error", "param": "api_key"}}\n\n'
|
||||
error = _extract_error_from_sse_chunk(chunk)
|
||||
|
||||
assert error["code"] == 403
|
||||
assert error["message"] == "forbidden"
|
||||
assert error["type"] == "auth_error"
|
||||
assert error["param"] == "api_key"
|
||||
|
||||
def test_extract_error_from_sse_chunk_with_string_code(self):
|
||||
"""Test error code as string type"""
|
||||
chunk = 'data: {"error": {"code": "429", "message": "too many requests"}}\n\n'
|
||||
error = _extract_error_from_sse_chunk(chunk)
|
||||
|
||||
assert error["code"] == "429"
|
||||
assert error["message"] == "too many requests"
|
||||
|
||||
def test_extract_error_from_sse_chunk_with_bytes(self):
|
||||
"""Test input as bytes type"""
|
||||
chunk = b'data: {"error": {"code": 500, "message": "internal error"}}\n\n'
|
||||
error = _extract_error_from_sse_chunk(chunk)
|
||||
|
||||
assert error["code"] == 500
|
||||
assert error["message"] == "internal error"
|
||||
|
||||
def test_extract_error_from_sse_chunk_with_done(self):
|
||||
"""Test [DONE] marker should return default error"""
|
||||
chunk = "data: [DONE]\n\n"
|
||||
error = _extract_error_from_sse_chunk(chunk)
|
||||
|
||||
assert error["message"] == "Unknown error"
|
||||
assert error["type"] == "internal_server_error"
|
||||
assert error["code"] == "500"
|
||||
assert error["param"] is None
|
||||
|
||||
def test_extract_error_from_sse_chunk_without_error_field(self):
|
||||
"""Test missing error field should return default error"""
|
||||
chunk = 'data: {"content": "some content"}\n\n'
|
||||
error = _extract_error_from_sse_chunk(chunk)
|
||||
|
||||
assert error["message"] == "Unknown error"
|
||||
assert error["type"] == "internal_server_error"
|
||||
assert error["code"] == "500"
|
||||
|
||||
def test_extract_error_from_sse_chunk_with_invalid_json(self):
|
||||
"""Test invalid JSON should return default error"""
|
||||
chunk = 'data: {invalid json}\n\n'
|
||||
error = _extract_error_from_sse_chunk(chunk)
|
||||
|
||||
assert error["message"] == "Unknown error"
|
||||
assert error["type"] == "internal_server_error"
|
||||
assert error["code"] == "500"
|
||||
|
||||
def test_extract_error_from_sse_chunk_without_data_prefix(self):
|
||||
"""Test missing 'data:' prefix should return default error"""
|
||||
chunk = '{"error": {"code": 400, "message": "bad request"}}\n\n'
|
||||
error = _extract_error_from_sse_chunk(chunk)
|
||||
|
||||
assert error["message"] == "Unknown error"
|
||||
assert error["type"] == "internal_server_error"
|
||||
assert error["code"] == "500"
|
||||
|
||||
def test_extract_error_from_sse_chunk_with_empty_string(self):
|
||||
"""Test empty string should return default error"""
|
||||
chunk = ""
|
||||
error = _extract_error_from_sse_chunk(chunk)
|
||||
|
||||
assert error["message"] == "Unknown error"
|
||||
assert error["type"] == "internal_server_error"
|
||||
assert error["code"] == "500"
|
||||
|
||||
def test_extract_error_from_sse_chunk_with_minimal_error(self):
|
||||
"""Test minimal error object"""
|
||||
chunk = 'data: {"error": {"message": "error occurred"}}\n\n'
|
||||
error = _extract_error_from_sse_chunk(chunk)
|
||||
|
||||
assert error["message"] == "error occurred"
|
||||
# Other fields should be obtained from the original error object (if exists)
|
||||
|
||||
|
||||
for i, call in enumerate(actual_calls):
|
||||
args, kwargs = call
|
||||
assert (
|
||||
args[0] == "streaming.chunk.yield"
|
||||
), f"Call {i} should have operation name 'streaming.chunk.yield', got {args[0]}"
|
||||
|
|
|
|||
|
|
@ -43,6 +43,7 @@ test.describe("Internal Users Page", () => {
|
|||
await expect(prevButton).toBeDisabled();
|
||||
}
|
||||
|
||||
await page.waitForTimeout(1000);
|
||||
// Check if there are more pages
|
||||
const hasMorePages = infoText.includes("of") && !infoText.endsWith("25 of 25");
|
||||
if (hasMorePages) {
|
||||
|
|
|
|||
|
|
@ -279,12 +279,13 @@ const ModelsAndEndpointsView: React.FC<ModelDashboardProps> = ({ premiumUser, te
|
|||
{/* Missing Provider Banner */}
|
||||
<div className="mb-4 px-4 py-3 bg-blue-50 rounded-lg border border-blue-100 flex items-center gap-4">
|
||||
<div className="flex-shrink-0 w-10 h-10 bg-white rounded-full flex items-center justify-center border border-blue-200">
|
||||
<PlusCircleOutlined style={{ fontSize: '18px', color: '#6366f1' }} />
|
||||
<PlusCircleOutlined style={{ fontSize: "18px", color: "#6366f1" }} />
|
||||
</div>
|
||||
<div className="flex-1 min-w-0">
|
||||
<h4 className="text-gray-900 font-semibold text-sm m-0">Missing a provider?</h4>
|
||||
<p className="text-gray-500 text-xs m-0 mt-0.5">
|
||||
The LiteLLM engineering team is constantly adding support for new LLM models, providers, endpoints. If you don't see the one you need, let us know and we'll prioritize it.
|
||||
The LiteLLM engineering team is constantly adding support for new LLM models, providers, endpoints. If
|
||||
you don't see the one you need, let us know and we'll prioritize it.
|
||||
</p>
|
||||
</div>
|
||||
<a
|
||||
|
|
@ -294,8 +295,19 @@ const ModelsAndEndpointsView: React.FC<ModelDashboardProps> = ({ premiumUser, te
|
|||
className="flex-shrink-0 inline-flex items-center gap-2 px-4 py-2 bg-[#6366f1] hover:bg-[#5558e3] text-white text-sm font-medium rounded-lg transition-colors"
|
||||
>
|
||||
Request Provider
|
||||
<svg xmlns="http://www.w3.org/2000/svg" className="h-4 w-4" fill="none" viewBox="0 0 24 24" stroke="currentColor" strokeWidth={2}>
|
||||
<path strokeLinecap="round" strokeLinejoin="round" d="M10 6H6a2 2 0 00-2 2v10a2 2 0 002 2h10a2 2 0 002-2v-4M14 4h6m0 0v6m0-6L10 14" />
|
||||
<svg
|
||||
xmlns="http://www.w3.org/2000/svg"
|
||||
className="h-4 w-4"
|
||||
fill="none"
|
||||
viewBox="0 0 24 24"
|
||||
stroke="currentColor"
|
||||
strokeWidth={2}
|
||||
>
|
||||
<path
|
||||
strokeLinecap="round"
|
||||
strokeLinejoin="round"
|
||||
d="M10 6H6a2 2 0 00-2 2v10a2 2 0 002 2h10a2 2 0 002-2v-4M14 4h6m0 0v6m0-6L10 14"
|
||||
/>
|
||||
</svg>
|
||||
</a>
|
||||
</div>
|
||||
|
|
|
|||
Loading…
Add table
Reference in a new issue