mirror of
https://github.com/BerriAI/litellm.git
synced 2026-10-09 03:18:44 +00:00
Merge branch 'main' into fix-spend-logs
This commit is contained in:
 OrionCodeDev
GitHub
commit
90292d281e
173 changed files with 14213 additions and 2388 deletions
|
|
@ -112,6 +112,24 @@ jobs:
|
|||
python -m mypy .
|
||||
cd ..
|
||||
no_output_timeout: 10m
|
||||
|
||||
semgrep:
|
||||
docker:
|
||||
- image: cimg/python:3.12
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
- run:
|
||||
name: Install Semgrep
|
||||
command: pip install semgrep
|
||||
- run:
|
||||
name: Run Semgrep (custom rules only)
|
||||
command: semgrep scan --config .semgrep/rules . --error
|
||||
|
||||
local_testing_part1:
|
||||
docker:
|
||||
- image: cimg/python:3.12
|
||||
|
|
@ -3932,6 +3950,9 @@ jobs:
|
|||
image: ubuntu-2204:2023.10.1
|
||||
resource_class: xlarge
|
||||
working_directory: ~/project
|
||||
parameters:
|
||||
browser:
|
||||
type: string
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
|
|
@ -3961,7 +3982,7 @@ jobs:
|
|||
echo "Expires at: $EXPIRES_AT"
|
||||
neon branches create \
|
||||
--project-id $NEON_PROJECT_ID \
|
||||
--name preview/commit-${CIRCLE_SHA1:0:7} \
|
||||
--name preview/commit-${CIRCLE_SHA1:0:7}-<< parameters.browser >> \
|
||||
--expires-at $EXPIRES_AT \
|
||||
--parent br-fancy-paper-ad1olsb3 \
|
||||
--api-key $NEON_API_KEY || true
|
||||
|
|
@ -3971,7 +3992,7 @@ jobs:
|
|||
E2E_UI_TEST_DATABASE_URL=$(neon connection-string \
|
||||
--project-id $NEON_PROJECT_ID \
|
||||
--api-key $NEON_API_KEY \
|
||||
--branch preview/commit-${CIRCLE_SHA1:0:7} \
|
||||
--branch preview/commit-${CIRCLE_SHA1:0:7}-<< parameters.browser >> \
|
||||
--database-name yuneng-trial-db \
|
||||
--role neondb_owner)
|
||||
echo $E2E_UI_TEST_DATABASE_URL
|
||||
|
|
@ -3983,7 +4004,7 @@ jobs:
|
|||
-e UI_USERNAME="admin" \
|
||||
-e UI_PASSWORD="gm" \
|
||||
-e LITELLM_LICENSE=$LITELLM_LICENSE \
|
||||
--name litellm-docker-database \
|
||||
--name litellm-docker-database-<< parameters.browser >> \
|
||||
-v $(pwd)/litellm/proxy/example_config_yaml/simple_config.yaml:/app/config.yaml \
|
||||
litellm-docker-database:ci \
|
||||
--config /app/config.yaml \
|
||||
|
|
@ -3999,7 +4020,7 @@ jobs:
|
|||
sudo rm dockerize-linux-amd64-v0.6.1.tar.gz
|
||||
- run:
|
||||
name: Start outputting logs
|
||||
command: docker logs -f litellm-docker-database
|
||||
command: docker logs -f litellm-docker-database-<< parameters.browser >>
|
||||
background: true
|
||||
- run:
|
||||
name: Wait for app to be ready
|
||||
|
|
@ -4008,6 +4029,7 @@ jobs:
|
|||
name: Run Playwright Tests
|
||||
command: |
|
||||
npx playwright test \
|
||||
--project << parameters.browser >> \
|
||||
--config ui/litellm-dashboard/e2e_tests/playwright.config.ts \
|
||||
--reporter=html \
|
||||
--output=test-results
|
||||
|
|
@ -4114,6 +4136,12 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- semgrep:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- local_testing_part1:
|
||||
filters:
|
||||
branches:
|
||||
|
|
@ -4213,6 +4241,20 @@ workflows:
|
|||
- main
|
||||
- /litellm_.*/
|
||||
- e2e_ui_testing:
|
||||
name: e2e_ui_testing_chromium
|
||||
browser: chromium
|
||||
context: e2e_ui_tests
|
||||
requires:
|
||||
- ui_build
|
||||
- build_docker_database_image
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- e2e_ui_testing:
|
||||
name: e2e_ui_testing_firefox
|
||||
browser: firefox
|
||||
context: e2e_ui_tests
|
||||
requires:
|
||||
- ui_build
|
||||
|
|
@ -4492,6 +4534,7 @@ workflows:
|
|||
- publish_to_pypi:
|
||||
requires:
|
||||
- mypy_linting
|
||||
- semgrep
|
||||
- local_testing_part1
|
||||
- local_testing_part2
|
||||
- build_and_test
|
||||
|
|
@ -4524,7 +4567,8 @@ workflows:
|
|||
- litellm_assistants_api_testing
|
||||
- auth_ui_unit_tests
|
||||
- db_migration_disable_update_check
|
||||
- e2e_ui_testing
|
||||
- e2e_ui_testing_chromium
|
||||
- e2e_ui_testing_firefox
|
||||
- litellm_proxy_unit_testing_key_generation
|
||||
- litellm_proxy_unit_testing_part1
|
||||
- litellm_proxy_unit_testing_part2
|
||||
|
|
|
|||
1
.github/pull_request_template.md
vendored
1
.github/pull_request_template.md
vendored
|
|
@ -9,6 +9,7 @@
|
|||
- [ ] I have Added testing in the [`tests/litellm/`](https://github.com/BerriAI/litellm/tree/main/tests/litellm) directory, **Adding at least 1 test is a hard requirement** - [see details](https://docs.litellm.ai/docs/extras/contributing_code)
|
||||
- [ ] My PR passes all unit tests on [`make test-unit`](https://docs.litellm.ai/docs/extras/contributing_code)
|
||||
- [ ] My PR's scope is as isolated as possible, it only solves 1 specific problem
|
||||
- [ ] I have requested a Greptile review by commenting `@greptileai` and received a **Confidence Score of at least 4/5** before requesting a maintainer review
|
||||
|
||||
## CI (LiteLLM team)
|
||||
|
||||
|
|
|
|||
52
.semgrep/rules/README.md
Normal file
52
.semgrep/rules/README.md
Normal file
|
|
@ -0,0 +1,52 @@
|
|||
# Custom Semgrep Rules
|
||||
|
||||
All `.yml` files under `.semgrep/rules/` run in CI (CircleCI `semgrep` job).
|
||||
|
||||
## Add a Rule
|
||||
|
||||
* Add a `.yml` file under `.semgrep/rules/<language>/<domain>/`
|
||||
|
||||
|
||||
[Rule syntax →](https://semgrep.dev/docs/writing-rules/rule-syntax/)
|
||||
|
||||
## Organizing Rules
|
||||
|
||||
### Structure: language → domain
|
||||
|
||||
```
|
||||
.semgrep/rules/<language>/<domain>/<rule-name>.yml
|
||||
```
|
||||
|
||||
Examples:
|
||||
|
||||
- `python/security/unsafe-yaml-load.yml`
|
||||
- `python/reliability/missing-timeout-http.yml`
|
||||
- `python/performance/blocking-io-in-async.yml`
|
||||
|
||||
### Rule metadata
|
||||
|
||||
Match tags to the folder for consistent filtering:
|
||||
|
||||
```yaml
|
||||
metadata:
|
||||
tags: [python, security]
|
||||
```
|
||||
|
||||
### Severity expectations
|
||||
|
||||
All rules must fail CI on findings. No warn-only rules.
|
||||
|
||||
- Use `severity: ERROR` in rule metadata
|
||||
- If a rule is noisy → refine until low false positives before adding
|
||||
|
||||
## Run Locally
|
||||
|
||||
```bash
|
||||
semgrep scan --config .semgrep/rules . --error
|
||||
```
|
||||
|
||||
With Semgrep registry:
|
||||
|
||||
```bash
|
||||
semgrep scan --config auto --config .semgrep/rules .
|
||||
```
|
||||
17
.semgrep/rules/python/reliability/unbounded-memory.yml
Normal file
17
.semgrep/rules/python/reliability/unbounded-memory.yml
Normal file
|
|
@ -0,0 +1,17 @@
|
|||
# Unbounded memory growth – data structures without a clear max limit
|
||||
# Can lead to OOM under load.
|
||||
|
||||
rules:
|
||||
- id: unbounded-asyncio-queue
|
||||
message: asyncio.Queue() with no maxsize can grow unbounded. Use asyncio.Queue(maxsize=N) for integrations (e.g. log queues).
|
||||
severity: ERROR
|
||||
languages: [python]
|
||||
pattern-either:
|
||||
- pattern: asyncio.Queue()
|
||||
- pattern: asyncio.Queue(maxsize=0)
|
||||
metadata:
|
||||
category: reliability
|
||||
cwe: "CWE-400: Uncontrolled Resource Consumption"
|
||||
tags: [python, reliability]
|
||||
confidence: HIGH
|
||||
source: https://docs.python.org/3/library/asyncio-queue.html
|
||||
|
|
@ -16,10 +16,14 @@ Usage:
|
|||
import asyncio
|
||||
import base64
|
||||
import json
|
||||
import os
|
||||
import pyaudio
|
||||
import websockets
|
||||
from typing import Optional
|
||||
|
||||
# Bounded queue size for audio chunks (configurable via env to avoid unbounded memory)
|
||||
AUDIO_QUEUE_MAXSIZE = int(os.getenv("LITELLM_ASYNCIO_QUEUE_MAXSIZE", 10_000))
|
||||
|
||||
# Audio configuration (matching Nova Sonic requirements)
|
||||
INPUT_SAMPLE_RATE = 16000 # Nova Sonic expects 16kHz input
|
||||
OUTPUT_SAMPLE_RATE = 24000 # Nova Sonic outputs 24kHz
|
||||
|
|
@ -40,7 +44,7 @@ class RealtimeClient:
|
|||
self.api_key = api_key
|
||||
self.ws: Optional[websockets.WebSocketClientProtocol] = None
|
||||
self.is_active = False
|
||||
self.audio_queue = asyncio.Queue()
|
||||
self.audio_queue = asyncio.Queue(maxsize=AUDIO_QUEUE_MAXSIZE)
|
||||
self.pyaudio = pyaudio.PyAudio()
|
||||
self.input_stream = None
|
||||
self.output_stream = None
|
||||
|
|
|
|||
|
|
@ -5,6 +5,13 @@ import Image from '@theme/IdealImage';
|
|||
|
||||
Benchmarks for LiteLLM Gateway (Proxy Server) tested against a fake OpenAI endpoint.
|
||||
|
||||
## Setting Up a Fake OpenAI Endpoint
|
||||
|
||||
For load testing and benchmarking, you can use a fake OpenAI proxy server. LiteLLM provides:
|
||||
|
||||
1. **Hosted endpoint**: Use our free hosted fake endpoint at `https://exampleopenaiendpoint-production.up.railway.app/`
|
||||
2. **Self-hosted**: Set up your own fake OpenAI proxy server using [github.com/BerriAI/example_openai_endpoint](https://github.com/BerriAI/example_openai_endpoint)
|
||||
|
||||
Use this config for testing:
|
||||
|
||||
```yaml
|
||||
|
|
@ -12,7 +19,7 @@ model_list:
|
|||
- model_name: "fake-openai-endpoint"
|
||||
litellm_params:
|
||||
model: openai/any
|
||||
api_base: https://your-fake-openai-endpoint.com/chat/completions
|
||||
api_base: https://exampleopenaiendpoint-production.up.railway.app/ # or your self-hosted endpoint
|
||||
api_key: "test"
|
||||
```
|
||||
|
||||
|
|
|
|||
|
|
@ -4,8 +4,9 @@ import Image from '@theme/IdealImage';
|
|||
|
||||
## Locust Load Test LiteLLM Proxy
|
||||
|
||||
1. Add `fake-openai-endpoint` to your proxy config.yaml and start your litellm proxy
|
||||
litellm provides a free hosted `fake-openai-endpoint` you can load test against
|
||||
1. Add `fake-openai-endpoint` to your proxy config.yaml and start your litellm proxy.
|
||||
|
||||
LiteLLM provides a free hosted `fake-openai-endpoint` you can load test against. You can also self-host your own fake OpenAI proxy server using [github.com/BerriAI/example_openai_endpoint](https://github.com/BerriAI/example_openai_endpoint).
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
|
|
|
|||
|
|
@ -29,12 +29,16 @@ Tutorial on how to get to 1K+ RPS with LiteLLM Proxy on locust
|
|||
|
||||
**Note:** we're currently migrating to aiohttp which has 10x higher throughput. We recommend using the `openai/` provider for load testing.
|
||||
|
||||
:::tip Setting Up a Fake OpenAI Endpoint
|
||||
You can use our hosted fake endpoint or self-host your own using [github.com/BerriAI/example_openai_endpoint](https://github.com/BerriAI/example_openai_endpoint).
|
||||
:::
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: "fake-openai-endpoint"
|
||||
litellm_params:
|
||||
model: openai/any
|
||||
api_base: https://your-fake-openai-endpoint.com/chat/completions
|
||||
api_base: https://exampleopenaiendpoint-production.up.railway.app/ # or your self-hosted endpoint
|
||||
api_key: "test"
|
||||
```
|
||||
|
||||
|
|
|
|||
|
|
@ -395,7 +395,7 @@ router_settings:
|
|||
| ATHINA_API_KEY | API key for Athina service
|
||||
| ATHINA_BASE_URL | Base URL for Athina service (defaults to `https://log.athina.ai`)
|
||||
| AUTH_STRATEGY | Strategy used for authentication (e.g., OAuth, API key)
|
||||
| AUTO_REDIRECT_UI_LOGIN_TO_SSO | Flag to enable automatic redirect of UI login page to SSO when SSO is configured. Default is **true**
|
||||
| AUTO_REDIRECT_UI_LOGIN_TO_SSO | Flag to enable automatic redirect of UI login page to SSO when SSO is configured. Default is **false**
|
||||
| AUDIO_SPEECH_CHUNK_SIZE | Chunk size for audio speech processing. Default is 1024
|
||||
| ANTHROPIC_API_KEY | API key for Anthropic service
|
||||
| ANTHROPIC_API_BASE | Base URL for Anthropic API. Default is https://api.anthropic.com
|
||||
|
|
@ -784,6 +784,7 @@ router_settings:
|
|||
| LITELLM_USER_AGENT | Custom user agent string for LiteLLM API requests. Used for partner telemetry attribution
|
||||
| LITELLM_PRINT_STANDARD_LOGGING_PAYLOAD | If true, prints the standard logging payload to the console - useful for debugging
|
||||
| LITELM_ENVIRONMENT | Environment for LiteLLM Instance. This is currently only logged to DeepEval to determine the environment for DeepEval integration.
|
||||
| LITELLM_ASYNCIO_QUEUE_MAXSIZE | Maximum size for asyncio queues (e.g. log queues, spend update queues, and cookbook examples such as realtime audio in `nova_sonic_realtime.py`). Bounds in-memory growth to prevent OOM. Default is 1000.
|
||||
| LOGFIRE_TOKEN | Token for Logfire logging service
|
||||
| LOGFIRE_BASE_URL | Base URL for Logfire logging service (useful for self hosted deployments)
|
||||
| LOGGING_WORKER_CONCURRENCY | Maximum number of concurrent coroutine slots for the logging worker on the asyncio event loop. Default is 100. Setting too high will flood the event loop with logging tasks which will lower the overall latency of the requests.
|
||||
|
|
@ -811,6 +812,7 @@ router_settings:
|
|||
| MAX_RETRY_DELAY | Maximum delay in seconds for retrying requests. Default is 8.0
|
||||
| MAX_LANGFUSE_INITIALIZED_CLIENTS | Maximum number of Langfuse clients to initialize on proxy. Default is 50. This is set since langfuse initializes 1 thread everytime a client is initialized. We've had an incident in the past where we reached 100% cpu utilization because Langfuse was initialized several times.
|
||||
| MAX_MCP_SEMANTIC_FILTER_TOOLS_HEADER_LENGTH | Maximum header length for MCP semantic filter tools. Default is 150
|
||||
| MAX_POLICY_ESTIMATE_IMPACT_ROWS | Maximum number of rows returned when estimating the impact of a policy. Default is 1000
|
||||
| MIN_NON_ZERO_TEMPERATURE | Minimum non-zero temperature value. Default is 0.0001
|
||||
| MINIMUM_PROMPT_CACHE_TOKEN_COUNT | Minimum token count for caching a prompt. Default is 1024
|
||||
| MISTRAL_API_BASE | Base URL for Mistral API. Default is https://api.mistral.ai
|
||||
|
|
@ -827,6 +829,8 @@ router_settings:
|
|||
| MICROSOFT_USER_ID_ATTRIBUTE | Field name for user ID in Microsoft SSO response. Default is `id`
|
||||
| MICROSOFT_USER_LAST_NAME_ATTRIBUTE | Field name for user last name in Microsoft SSO response. Default is `surname`
|
||||
| MICROSOFT_USERINFO_ENDPOINT | Custom userinfo endpoint URL for Microsoft SSO (overrides default Microsoft Graph userinfo endpoint)
|
||||
| MODEL_COST_MAP_MAX_SHRINK_RATIO | Maximum allowed shrinkage ratio when validating a fetched model cost map against the local backup. Rejects the fetched map if it is smaller than this fraction of the backup. Default is 0.5
|
||||
| MODEL_COST_MAP_MIN_MODEL_COUNT | Minimum number of models a fetched cost map must contain to be considered valid. Default is 50
|
||||
| NO_DOCS | Flag to disable Swagger UI documentation
|
||||
| NO_REDOC | Flag to disable Redoc documentation
|
||||
| NO_PROXY | List of addresses to bypass proxy
|
||||
|
|
|
|||
|
|
@ -1,3 +1,7 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# [Beta] Guardrail Policies
|
||||
|
||||
Use policies to group guardrails and control which ones run for specific teams, keys, or models.
|
||||
|
|
@ -10,6 +14,9 @@ Use policies to group guardrails and control which ones run for specific teams,
|
|||
|
||||
## Quick Start
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="config" label="config.yaml">
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
|
|
@ -43,6 +50,26 @@ policy_attachments:
|
|||
scope: "*" # apply to all requests
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="ui" label="UI (LiteLLM Dashboard)">
|
||||
|
||||
**Step 1: Create a Policy**
|
||||
|
||||
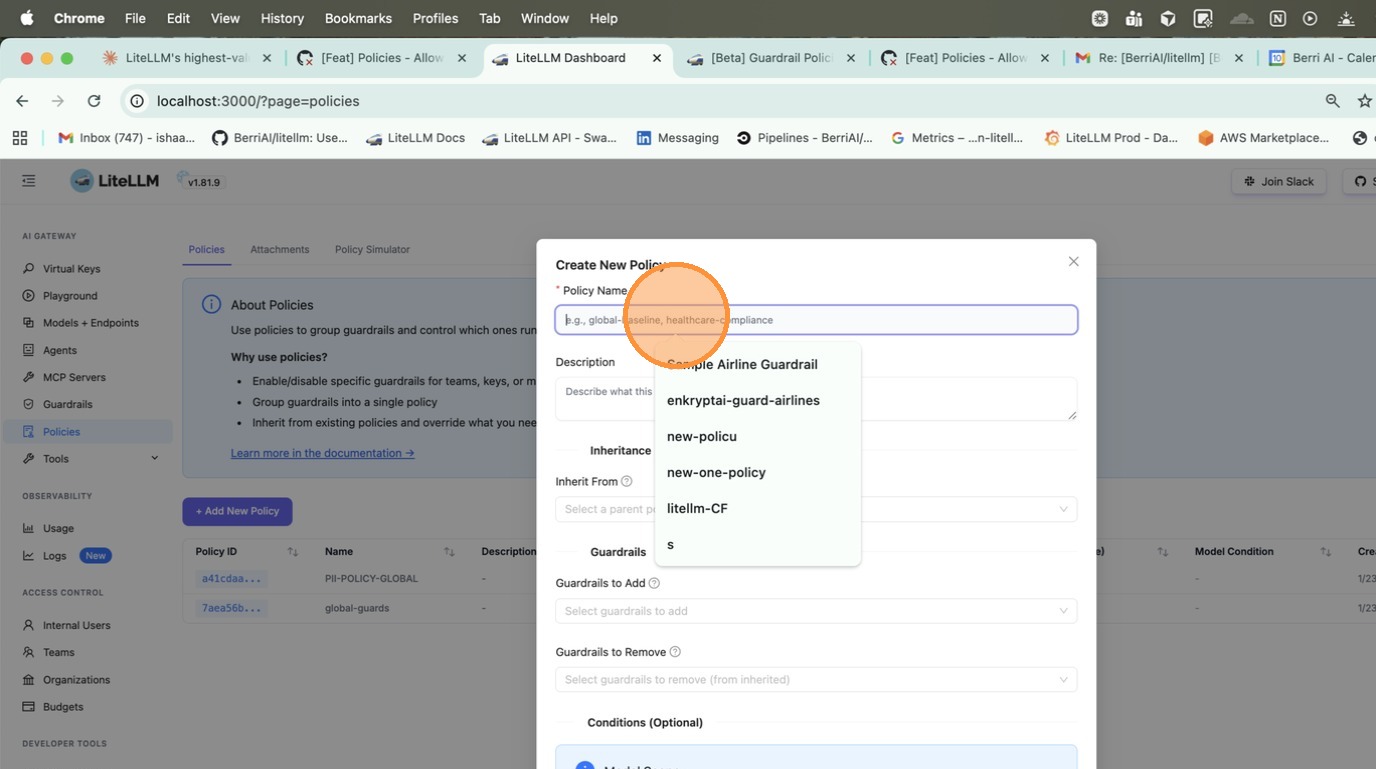
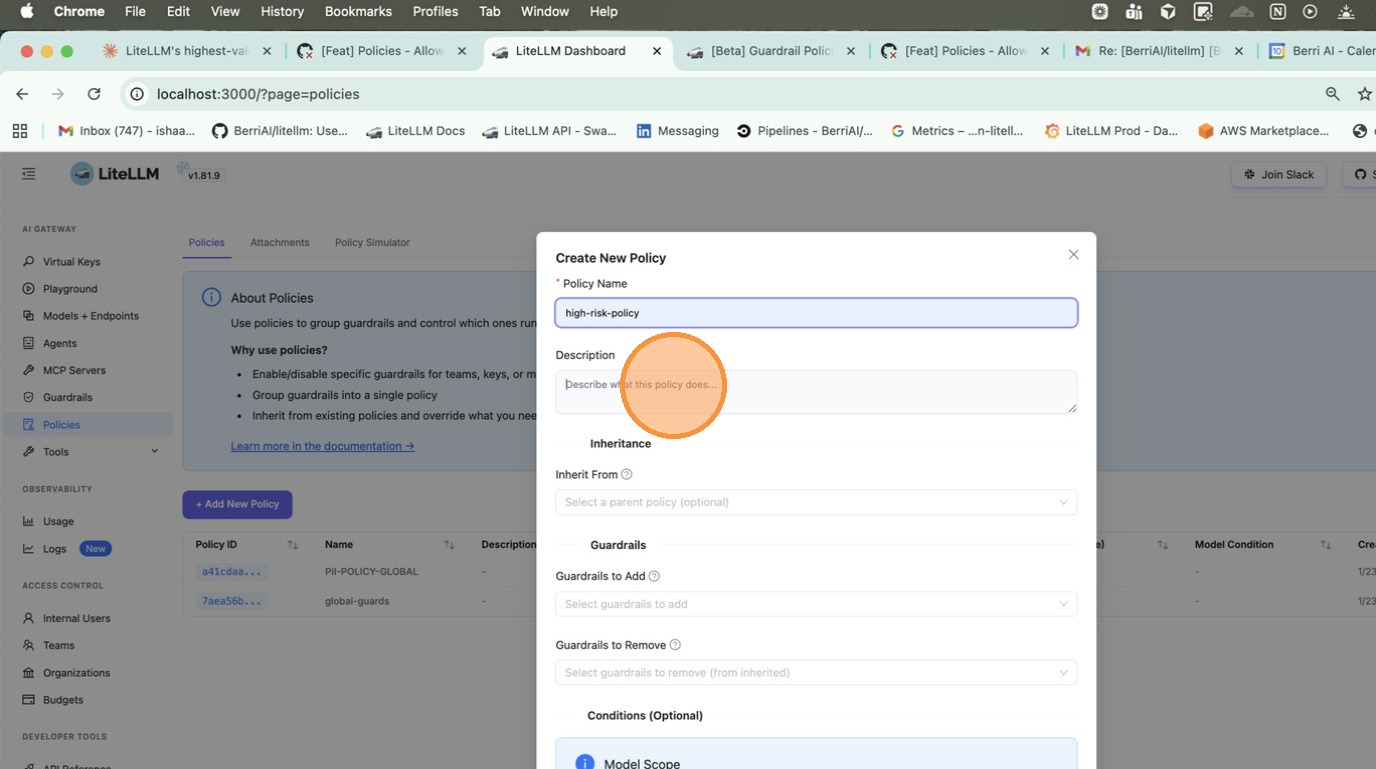
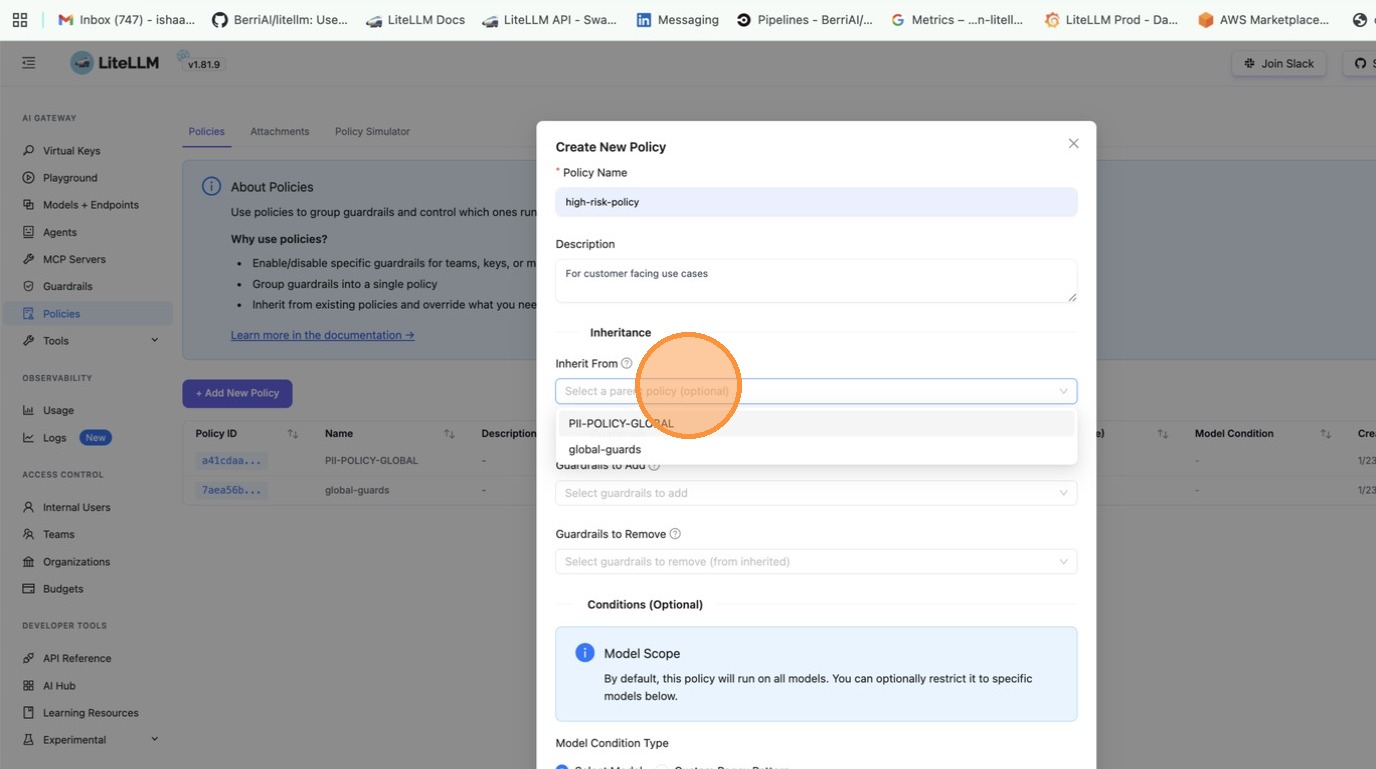
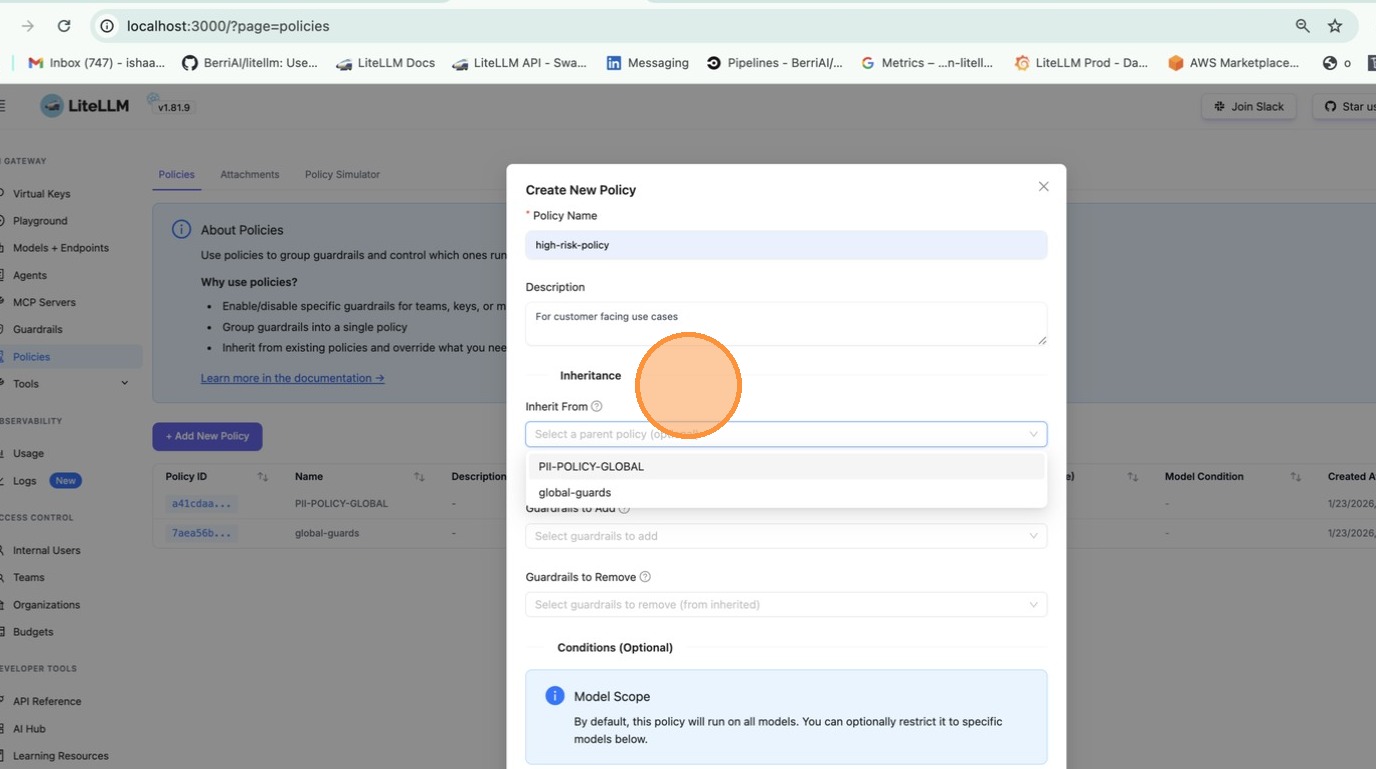
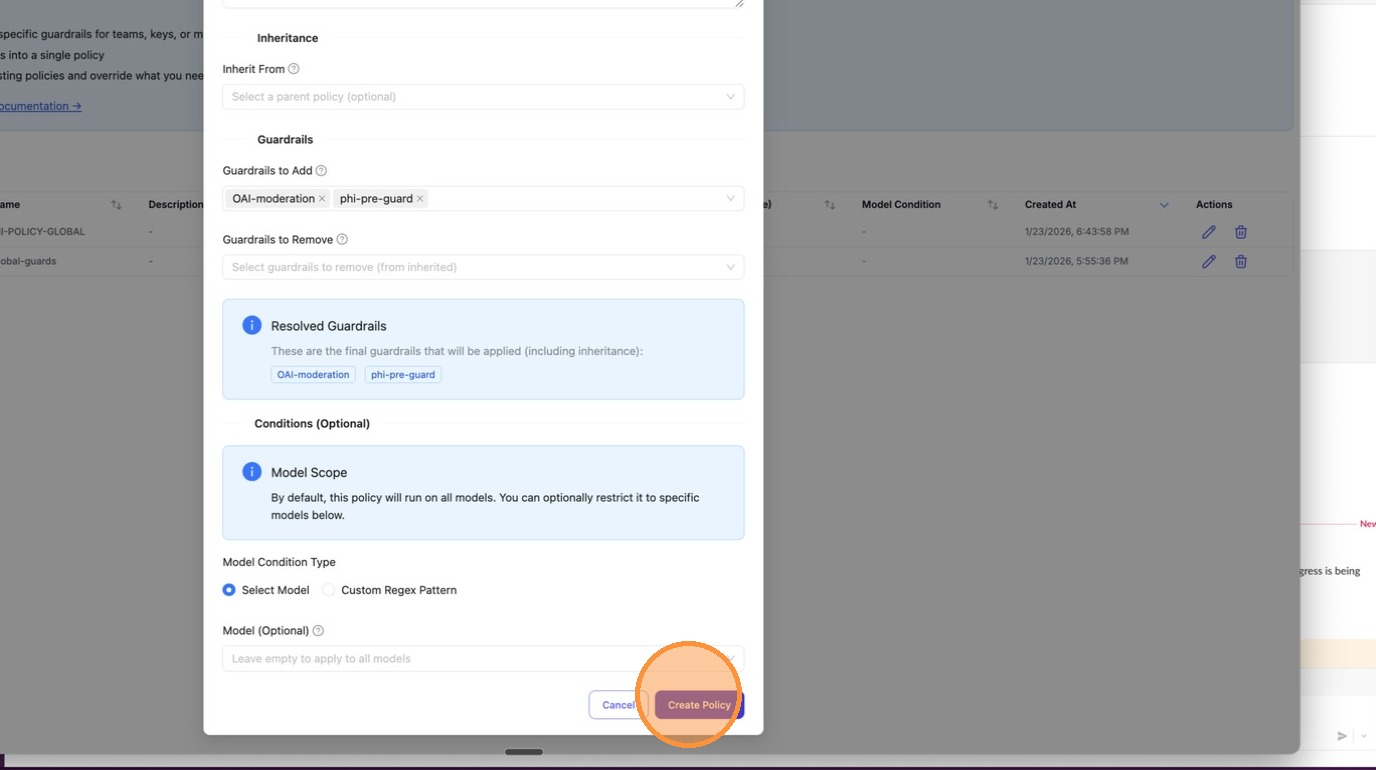
Go to **Policies** tab and click **+ Create New Policy**. Fill in the policy name, description, and select guardrails to add.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
Response headers show what ran:
|
||||
|
||||
```
|
||||
|
|
@ -58,6 +85,9 @@ x-litellm-applied-guardrails: pii_masking,prompt_injection
|
|||
|
||||
You have a global baseline, but want to add extra guardrails for a specific team.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="config" label="config.yaml">
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
policies:
|
||||
global-baseline:
|
||||
|
|
@ -81,6 +111,30 @@ policy_attachments:
|
|||
- finance # team alias from /team/new
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="ui" label="UI (LiteLLM Dashboard)">
|
||||
|
||||
**Option 1: Create a team-scoped attachment**
|
||||
|
||||
Go to **Policies** > **Attachments** tab and click **+ Create New Attachment**. Select the policy and the teams to scope it to.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
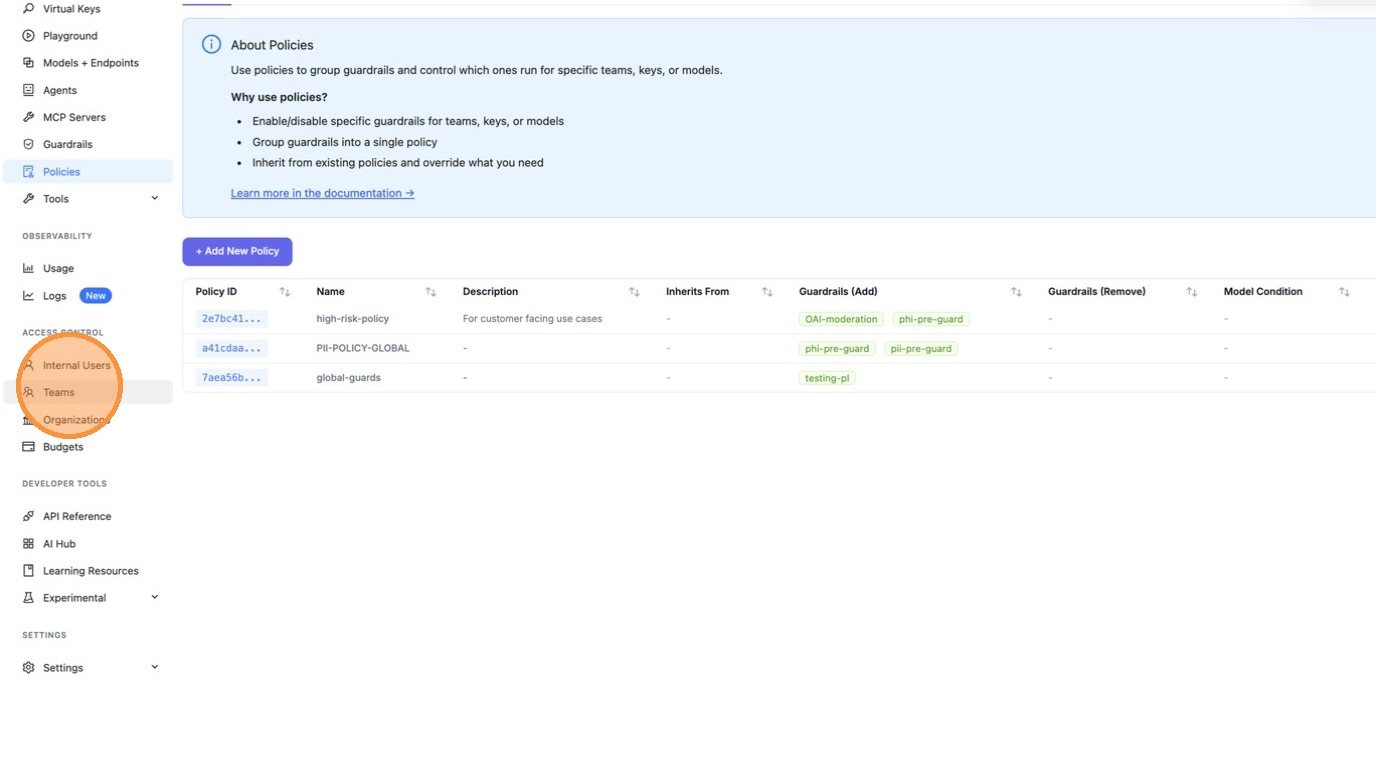
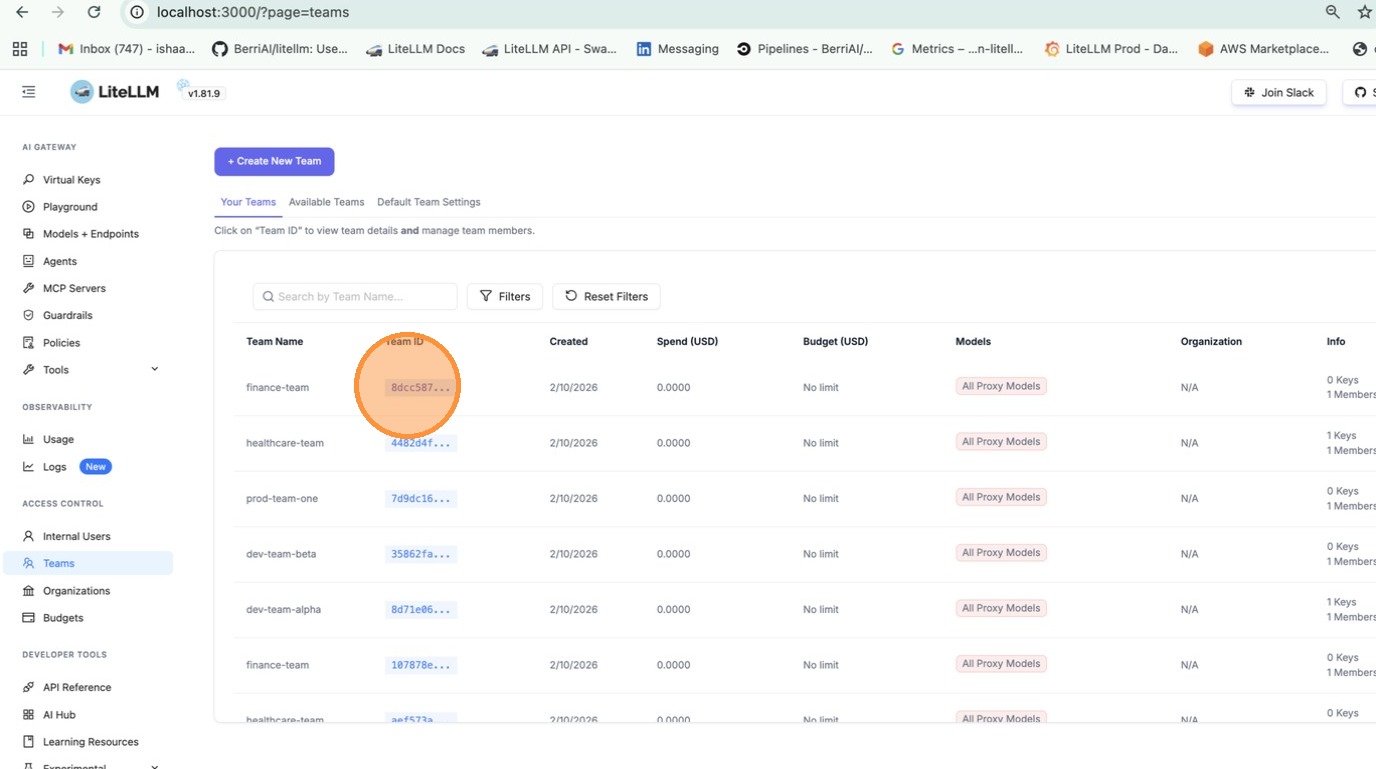
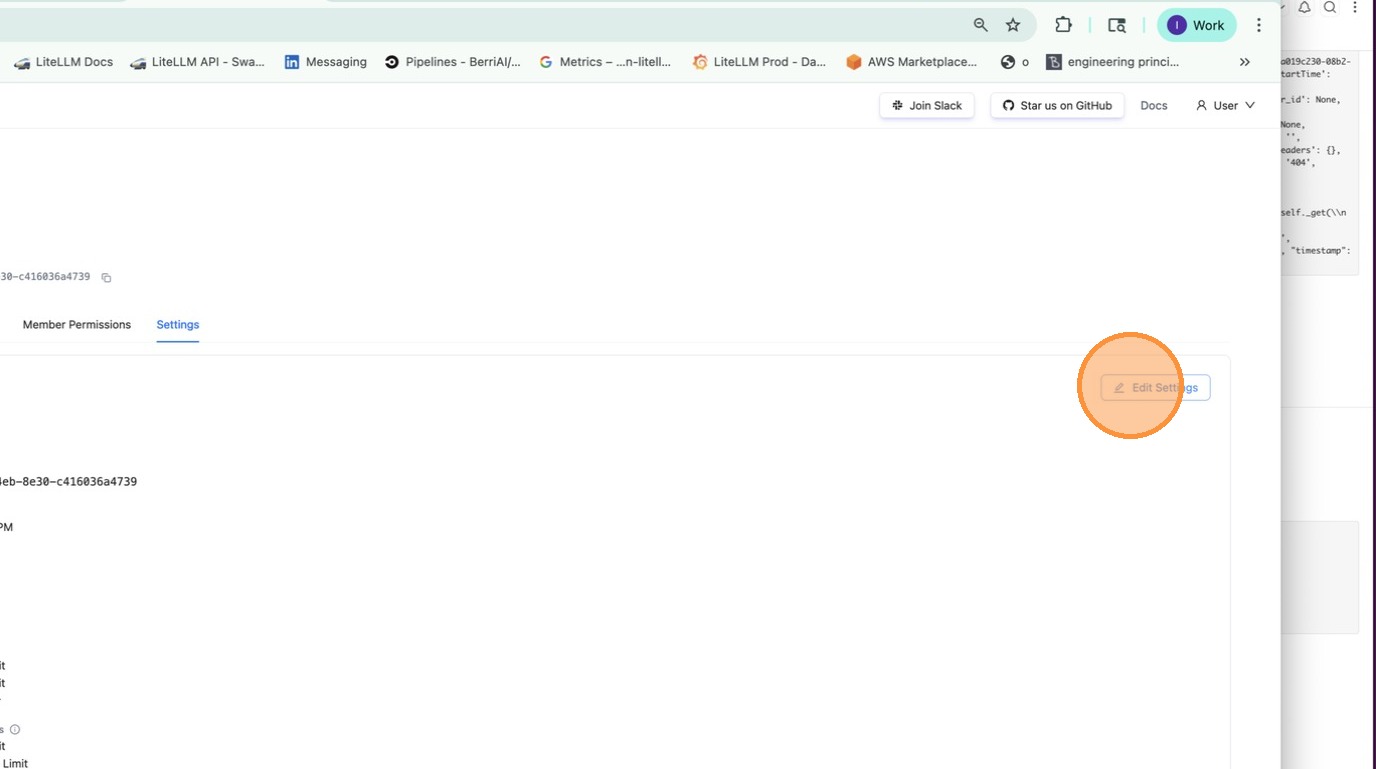
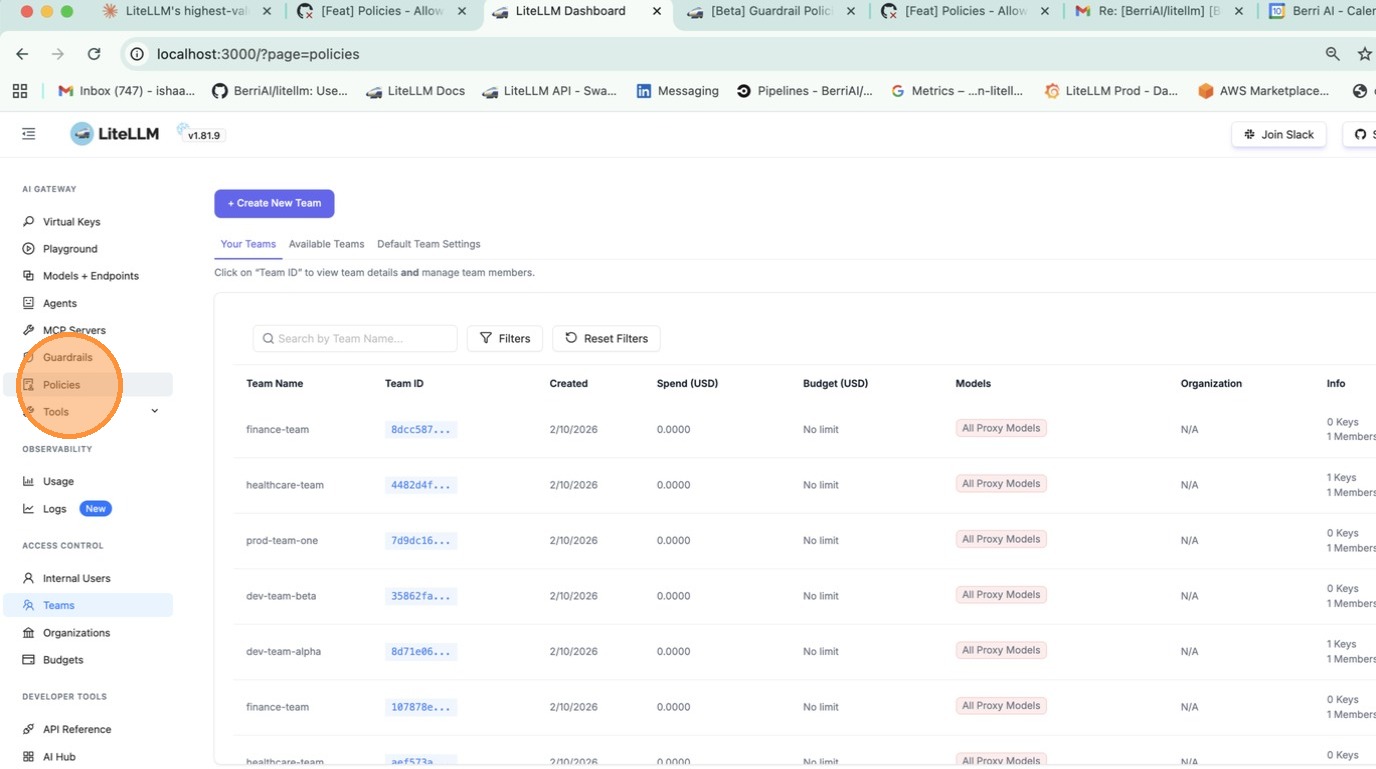
**Option 2: Attach from team settings**
|
||||
|
||||
Go to **Teams** > click on a team > **Settings** tab > under **Policies**, select the policies to attach.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
<Image img={require('../../../img/policy_team_attach.png')} />
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
Now the `finance` team gets `pii_masking` + `strict_compliance_check` + `audit_logger`, while everyone else just gets `pii_masking`.
|
||||
|
||||
## Remove guardrails for a specific team
|
||||
|
|
@ -201,6 +255,60 @@ policy_attachments:
|
|||
- "test-*" # key alias pattern
|
||||
```
|
||||
|
||||
**Tag-based** (matches keys/teams by metadata tags, wildcards supported):
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
policy_attachments:
|
||||
- policy: hipaa-compliance
|
||||
tags:
|
||||
- "healthcare"
|
||||
- "health-*" # wildcard - matches health-team, health-dev, etc.
|
||||
```
|
||||
|
||||
Tags are read from key and team `metadata.tags`. For example, a key created with `metadata: {"tags": ["healthcare"]}` would match the attachment above.
|
||||
|
||||
## Test Policy Matching
|
||||
|
||||
Debug which policies and guardrails apply for a given context. Use this to verify your policy configuration before deploying.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI (LiteLLM Dashboard)">
|
||||
|
||||
Go to **Policies** > **Test** tab. Enter a team alias, key alias, model, or tags and click **Test** to see which policies match and what guardrails would be applied.
|
||||
|
||||
<Image img={require('../../../img/policy_test_matching.png')} />
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
```bash
|
||||
curl -X POST "http://localhost:4000/policies/resolve" \
|
||||
-H "Authorization: Bearer <your_api_key>" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"tags": ["healthcare"],
|
||||
"model": "gpt-4"
|
||||
}'
|
||||
```
|
||||
|
||||
Response:
|
||||
|
||||
```json
|
||||
{
|
||||
"effective_guardrails": ["pii_masking"],
|
||||
"matched_policies": [
|
||||
{
|
||||
"policy_name": "hipaa-compliance",
|
||||
"matched_via": "tag:healthcare",
|
||||
"guardrails_added": ["pii_masking"]
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Config Reference
|
||||
|
||||
### `policies`
|
||||
|
|
@ -233,14 +341,18 @@ policy_attachments:
|
|||
scope: ...
|
||||
teams: [...]
|
||||
keys: [...]
|
||||
models: [...]
|
||||
tags: [...]
|
||||
```
|
||||
|
||||
| Field | Type | Description |
|
||||
|-------|------|-------------|
|
||||
| `policy` | `string` | **Required.** Name of the policy to attach. |
|
||||
| `scope` | `string` | Use `"*"` to apply globally. |
|
||||
| `teams` | `list[string]` | Team aliases (from `/team/new`). |
|
||||
| `teams` | `list[string]` | Team aliases (from `/team/new`). Supports `*` wildcard. |
|
||||
| `keys` | `list[string]` | Key aliases (from `/key/generate`). Supports `*` wildcard. |
|
||||
| `models` | `list[string]` | Model names. Supports `*` wildcard. |
|
||||
| `tags` | `list[string]` | Tag patterns (from key/team `metadata.tags`). Supports `*` wildcard. |
|
||||
|
||||
### Response Headers
|
||||
|
||||
|
|
@ -248,6 +360,7 @@ policy_attachments:
|
|||
|--------|-------------|
|
||||
| `x-litellm-applied-policies` | Policies that matched this request |
|
||||
| `x-litellm-applied-guardrails` | Guardrails that actually ran |
|
||||
| `x-litellm-policy-sources` | Why each policy matched (e.g., `hipaa=tag:healthcare; baseline=scope:*`) |
|
||||
|
||||
## How it works
|
||||
|
||||
|
|
|
|||
139
docs/my-website/docs/proxy/guardrails/policy_tags.md
Normal file
139
docs/my-website/docs/proxy/guardrails/policy_tags.md
Normal file
|
|
@ -0,0 +1,139 @@
|
|||
# Tag-Based Policy Attachments
|
||||
|
||||
Apply guardrail policies automatically to any key or team that has a specific tag. Instead of attaching policies one-by-one, tag your keys and let the policy engine handle the rest.
|
||||
|
||||
**Example:** Your security team requires all healthcare-related keys to run PII masking and PHI detection. Tag those keys with `health`, create a single tag-based attachment, and every matching key gets the guardrails automatically.
|
||||
|
||||
## 1. Create a Policy with Guardrails
|
||||
|
||||
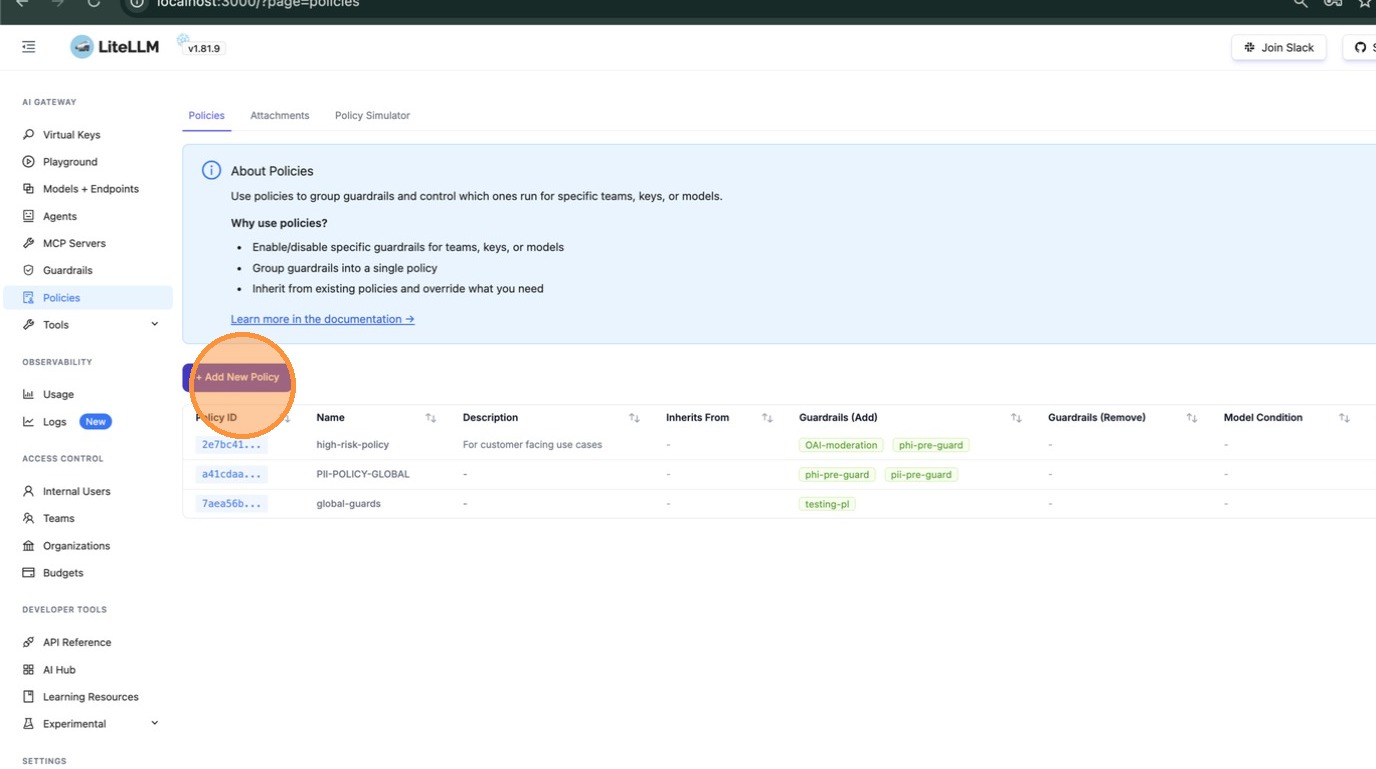
Navigate to **Policies** in the left sidebar. You'll see a list of existing policies along with their guardrails.
|
||||
|
||||
|
||||
|
||||
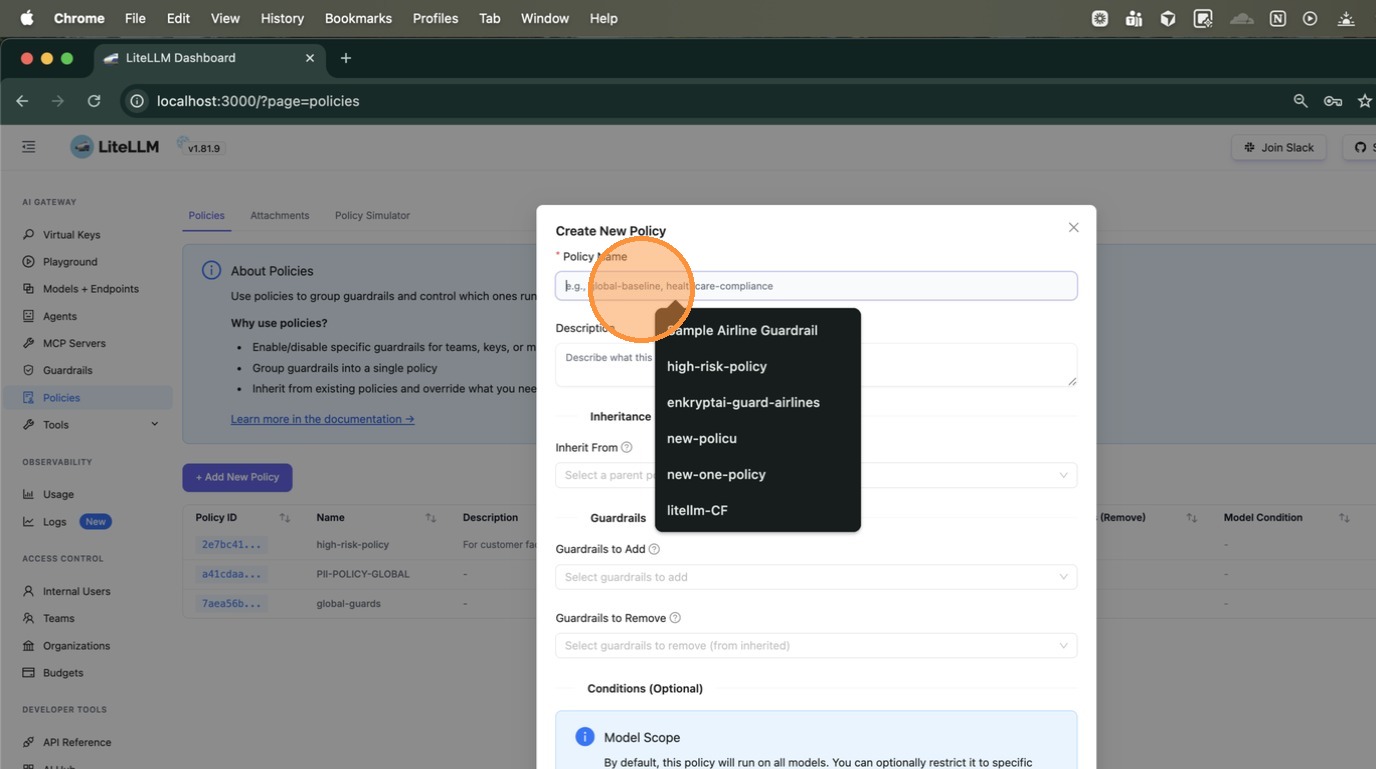
Click **+ Add New Policy**. In the modal, enter a name for your policy (e.g., `high-risk-policy2`). You can also type to search existing policy names if you want to reference them.
|
||||
|
||||
|
||||
|
||||
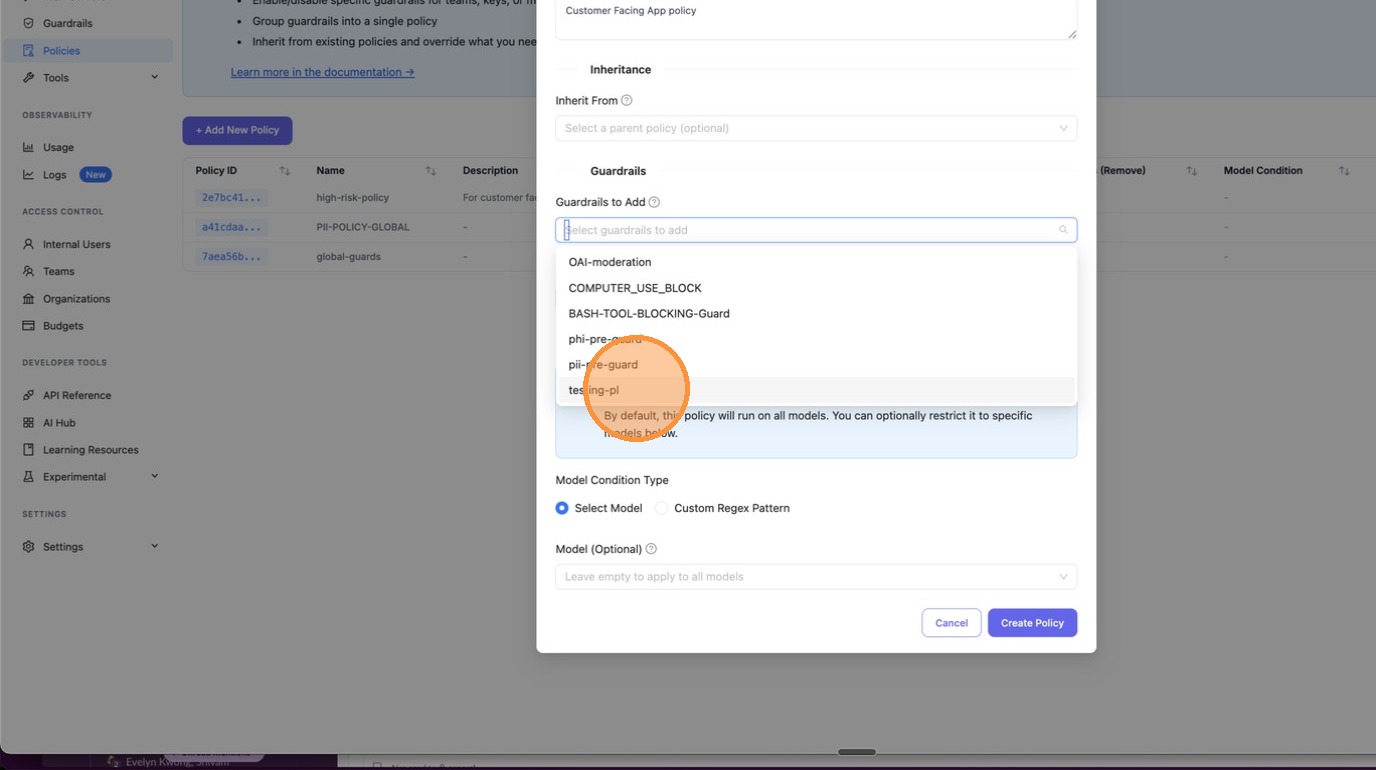
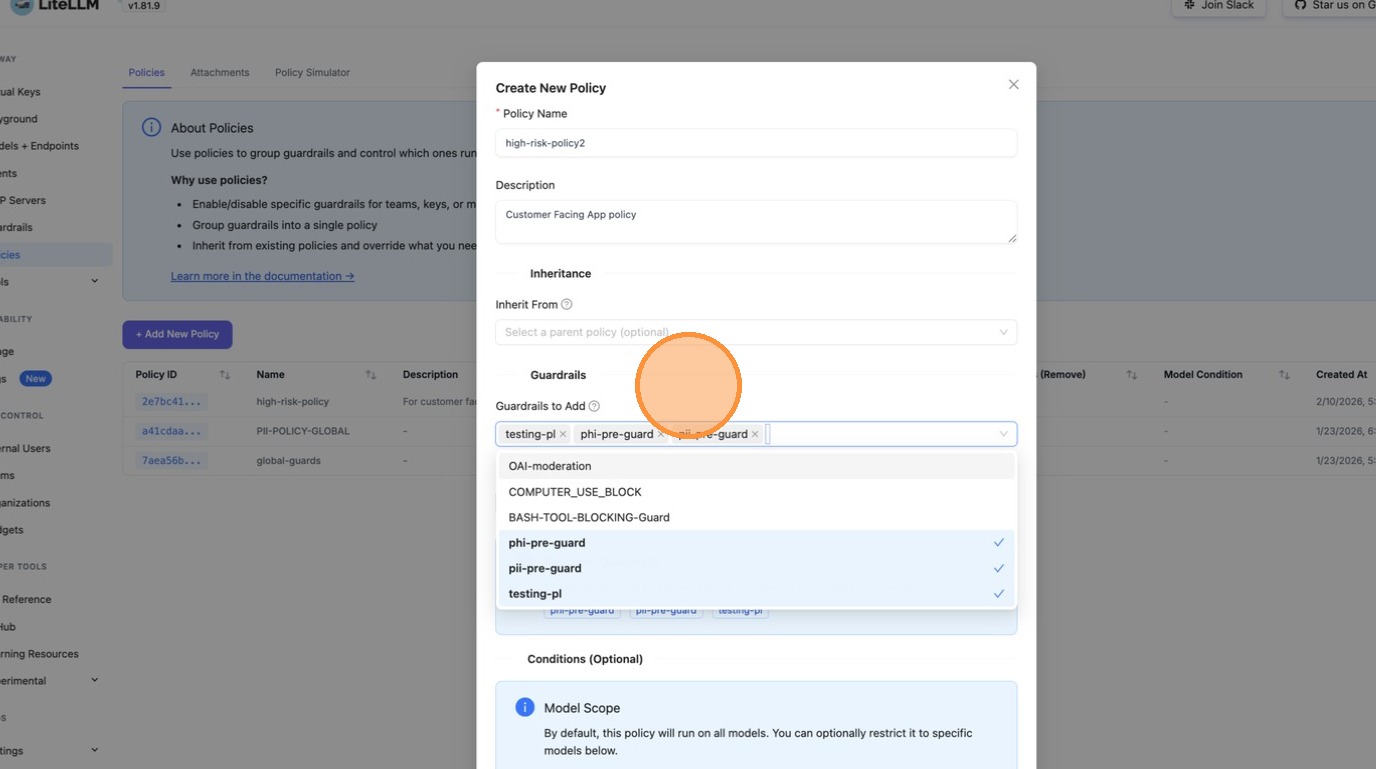
Scroll down to **Guardrails to Add**. Click the dropdown to see all available guardrails configured on your proxy — select the ones this policy should enforce.
|
||||
|
||||
|
||||
|
||||
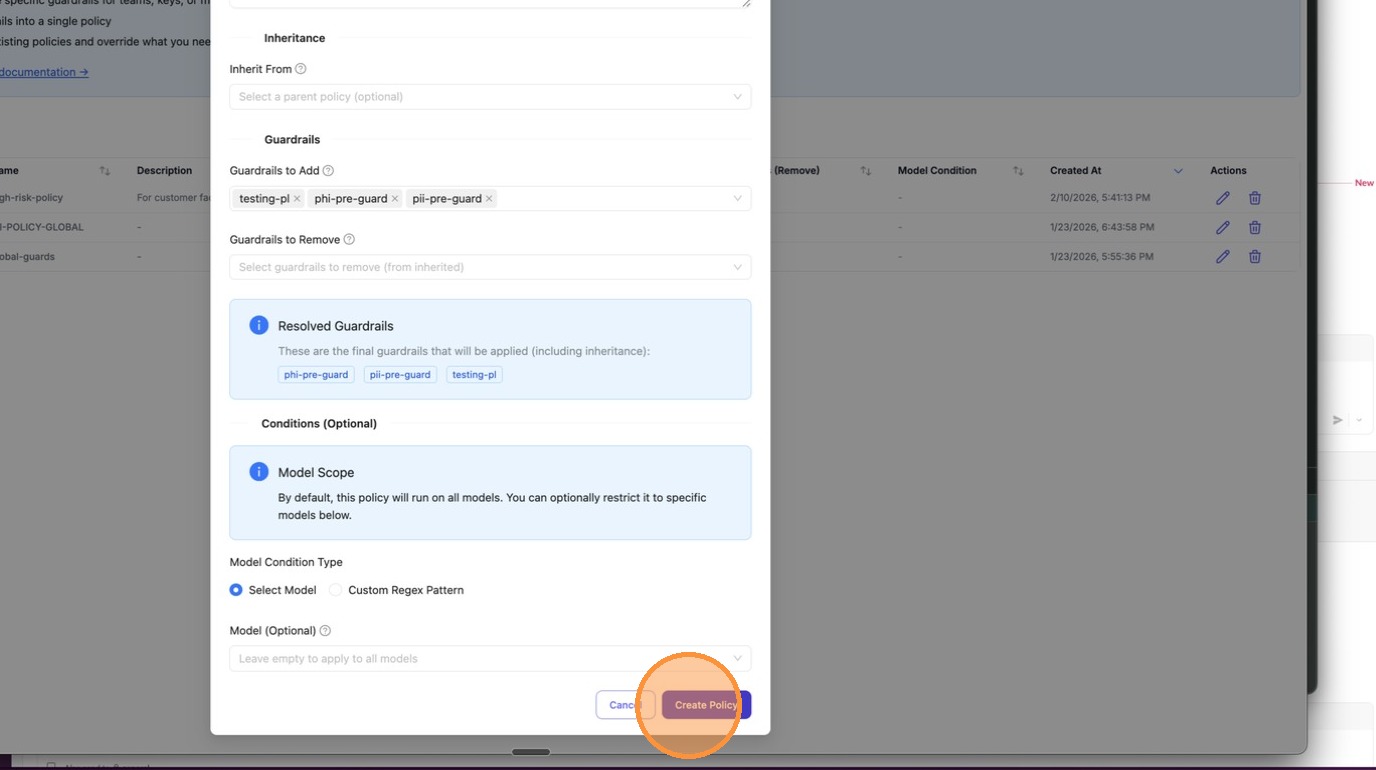
After selecting your guardrails, they appear as chips in the input field. The **Resolved Guardrails** section below shows the final set that will be applied (including any inherited from a parent policy).
|
||||
|
||||
|
||||
|
||||
Click **Create Policy** to save.
|
||||
|
||||
|
||||
|
||||
## 2. Add a Tag Attachment for the Policy
|
||||
|
||||
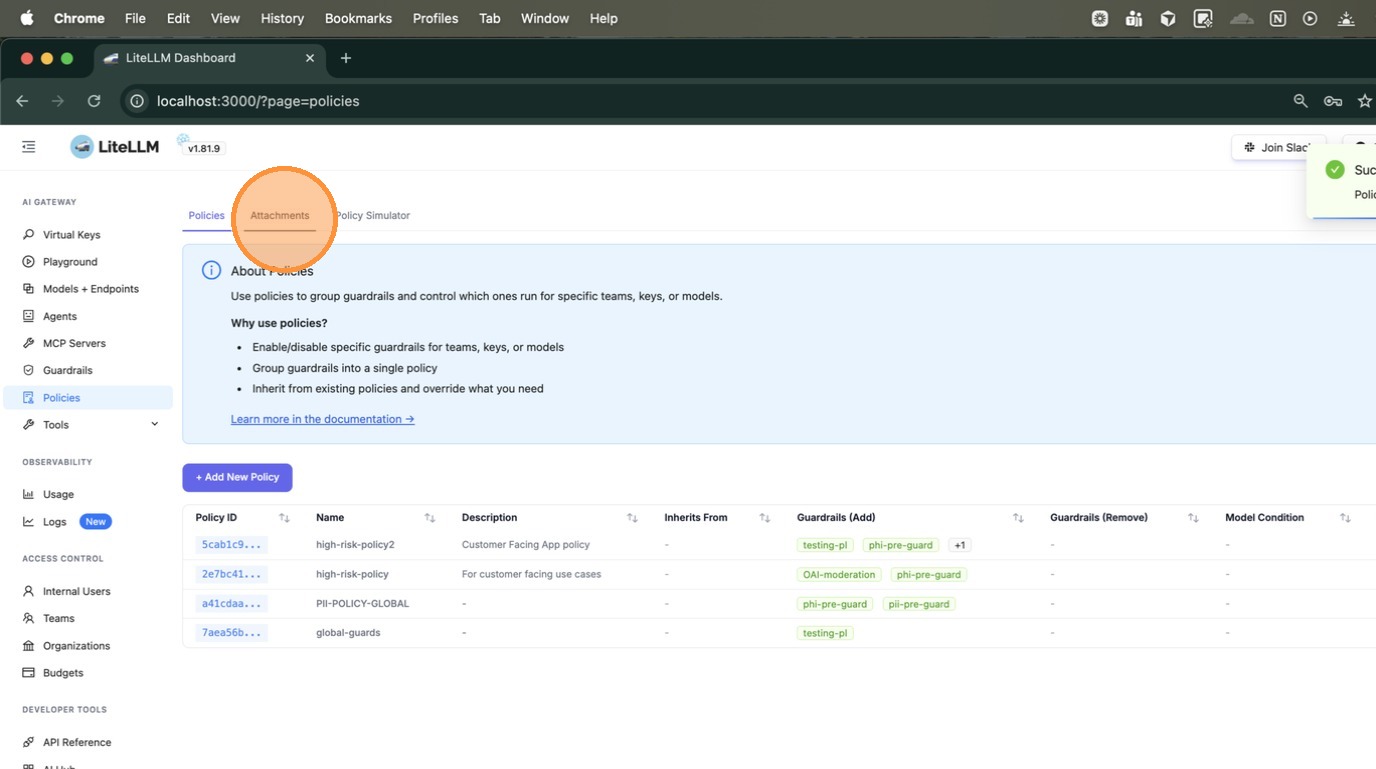
After creating the policy, switch to the **Attachments** tab. This is where you define *where* the policy applies.
|
||||
|
||||
|
||||
|
||||
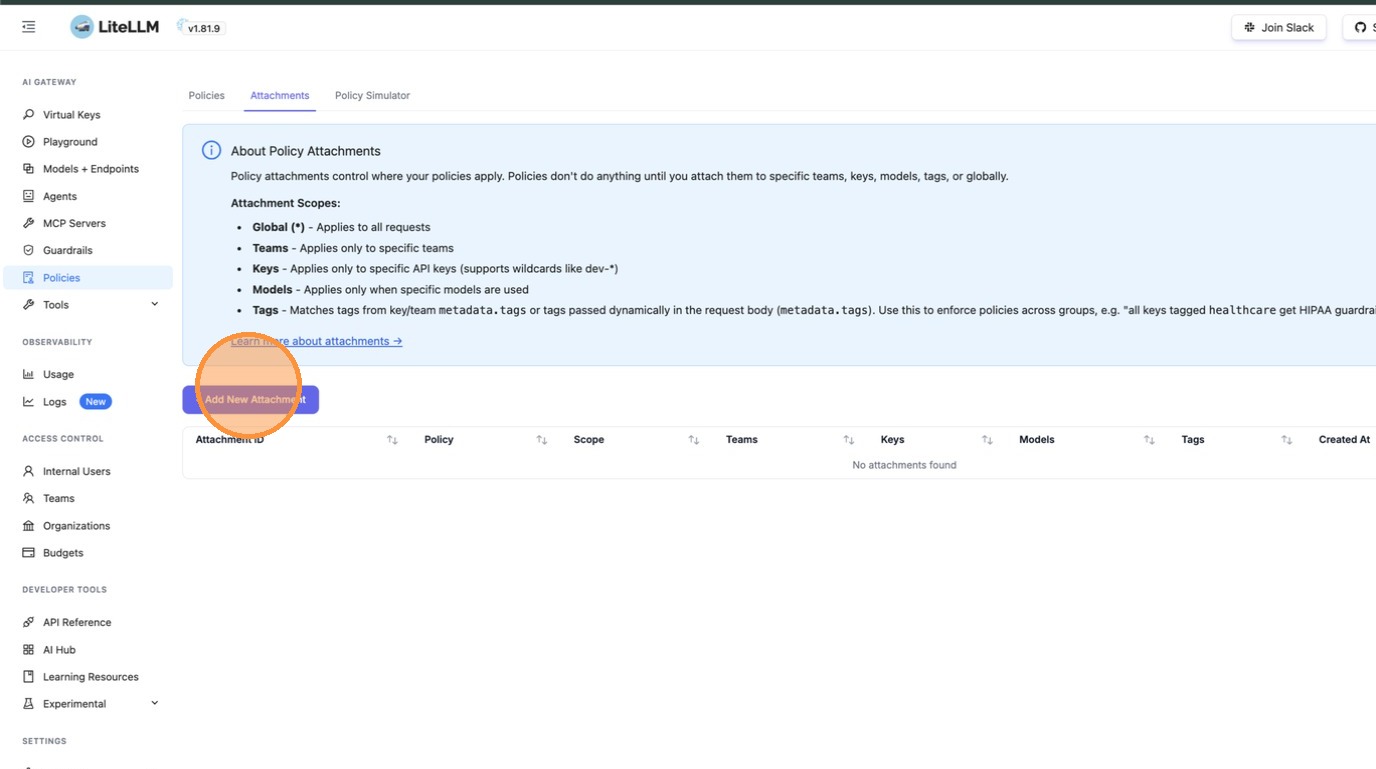
Click **+ Add New Attachment**. The Attachments page explains the available scopes: Global, Teams, Keys, Models, and **Tags**.
|
||||
|
||||
|
||||
|
||||
In the **Create Policy Attachment** modal, first select the policy you just created from the dropdown.
|
||||
|
||||
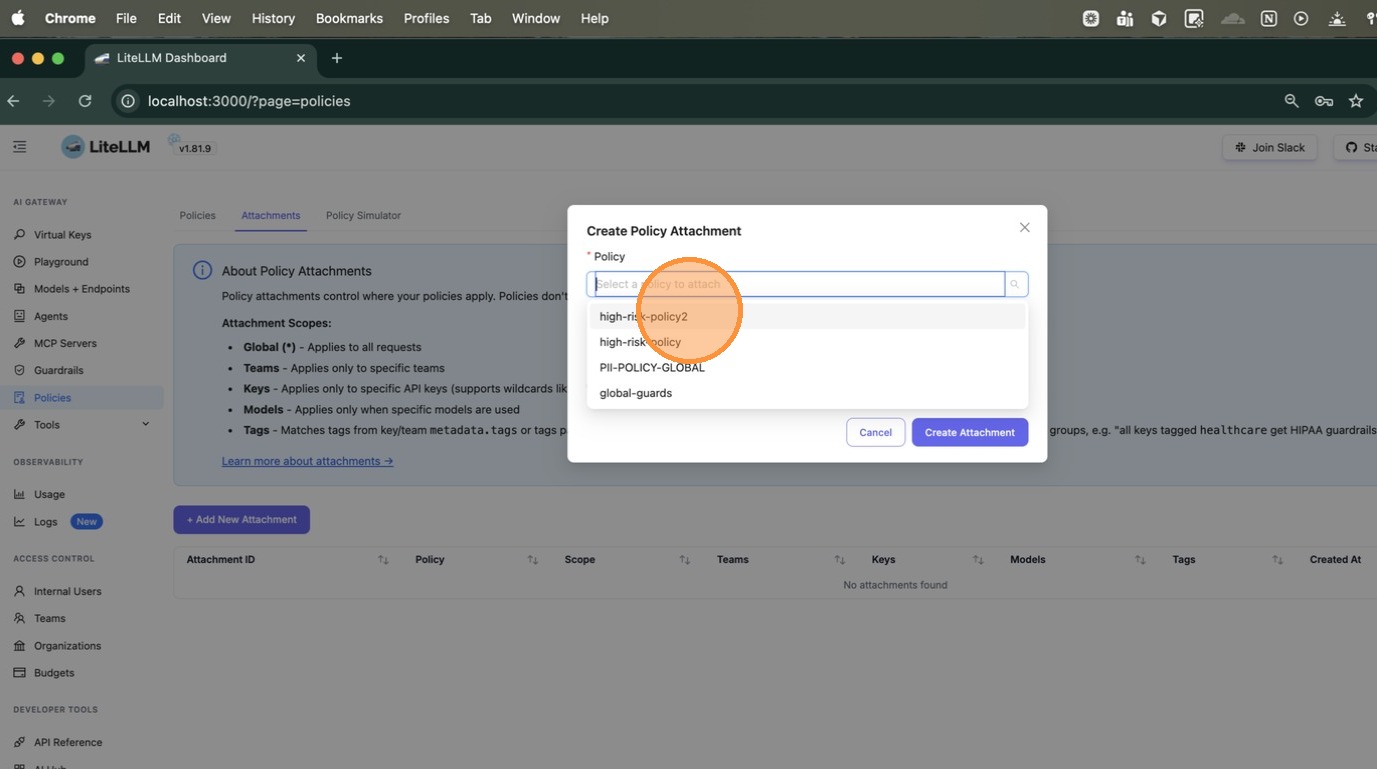
|
||||
|
||||
Choose **Specific (teams, keys, models, or tags)** as the scope type. This expands the form to show fields for Teams, Keys, Models, and Tags.
|
||||
|
||||
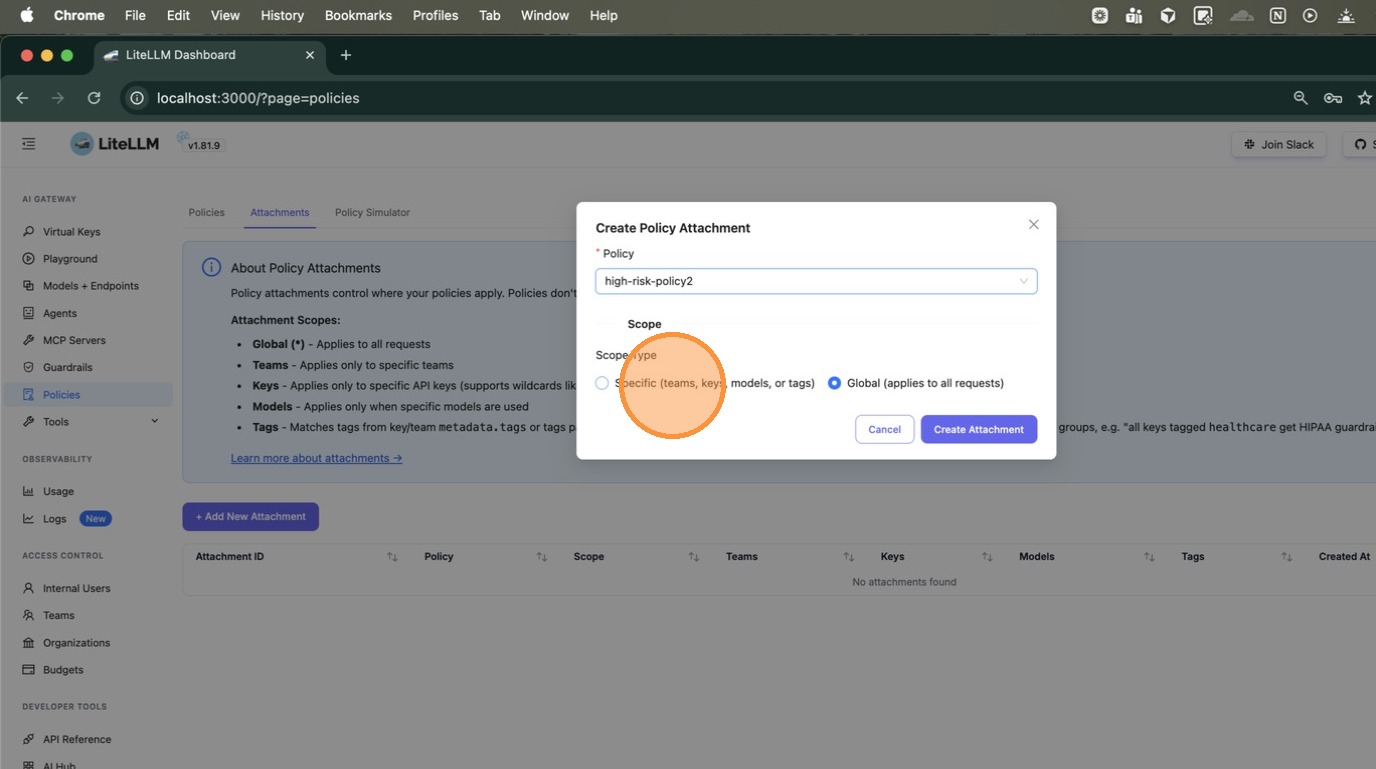
|
||||
|
||||
Scroll down to the **Tags** field and type the tag to match — here we enter `health`. You can enter any string, or use a wildcard pattern like `health-*` to match all tags starting with `health-` (e.g., `health-team`, `health-dev`).
|
||||
|
||||
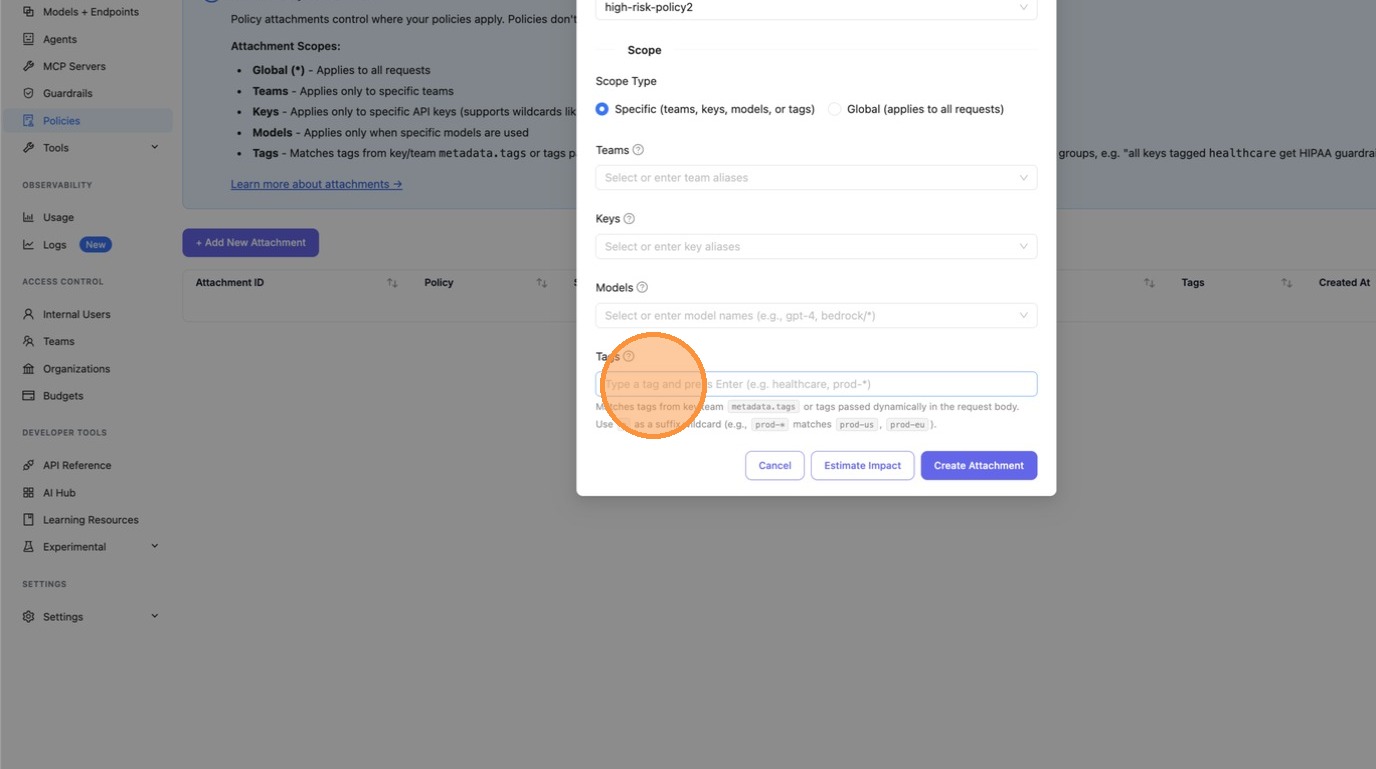
|
||||
|
||||
## 3. Check the Impact of the Attachment
|
||||
|
||||
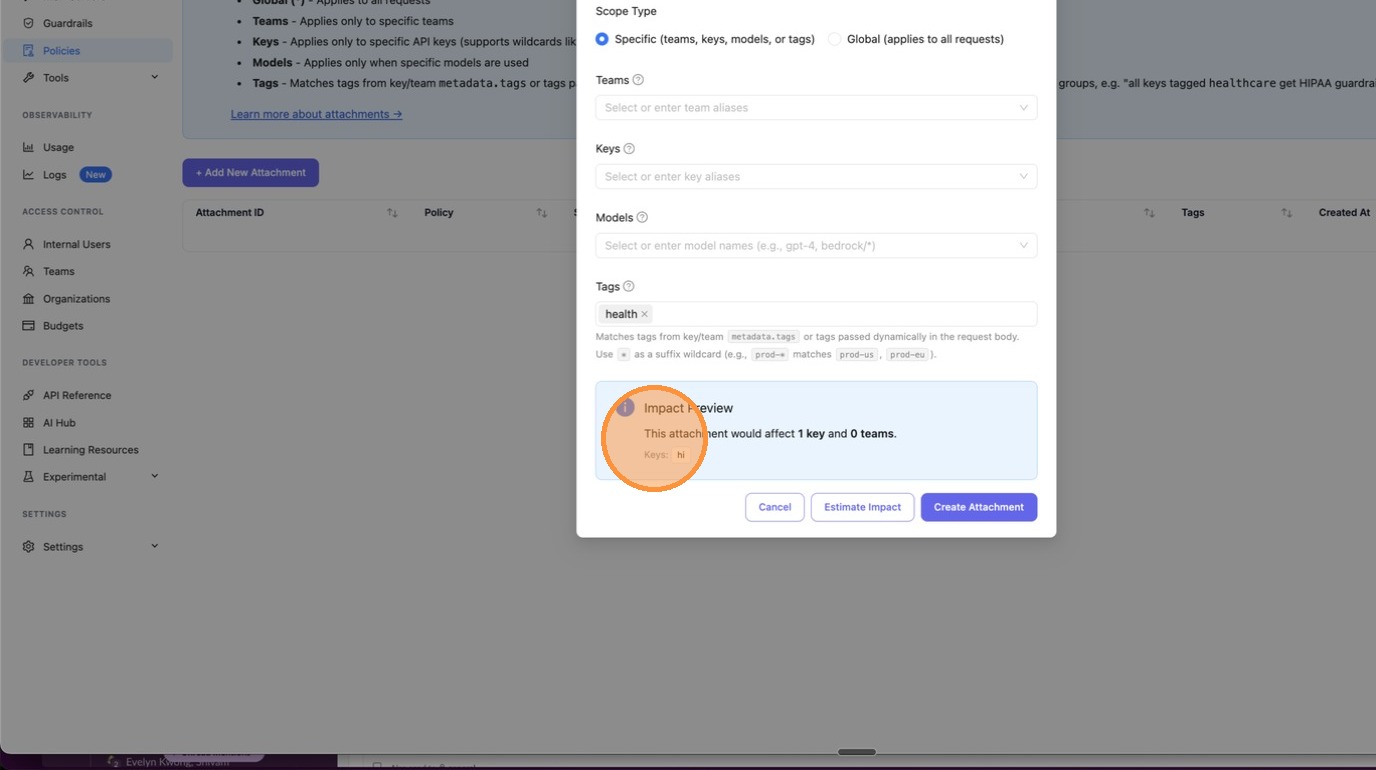
Before creating the attachment, click **Estimate Impact** to preview how many keys and teams would be affected. This is your blast-radius check — make sure the scope is what you expect before applying.
|
||||
|
||||
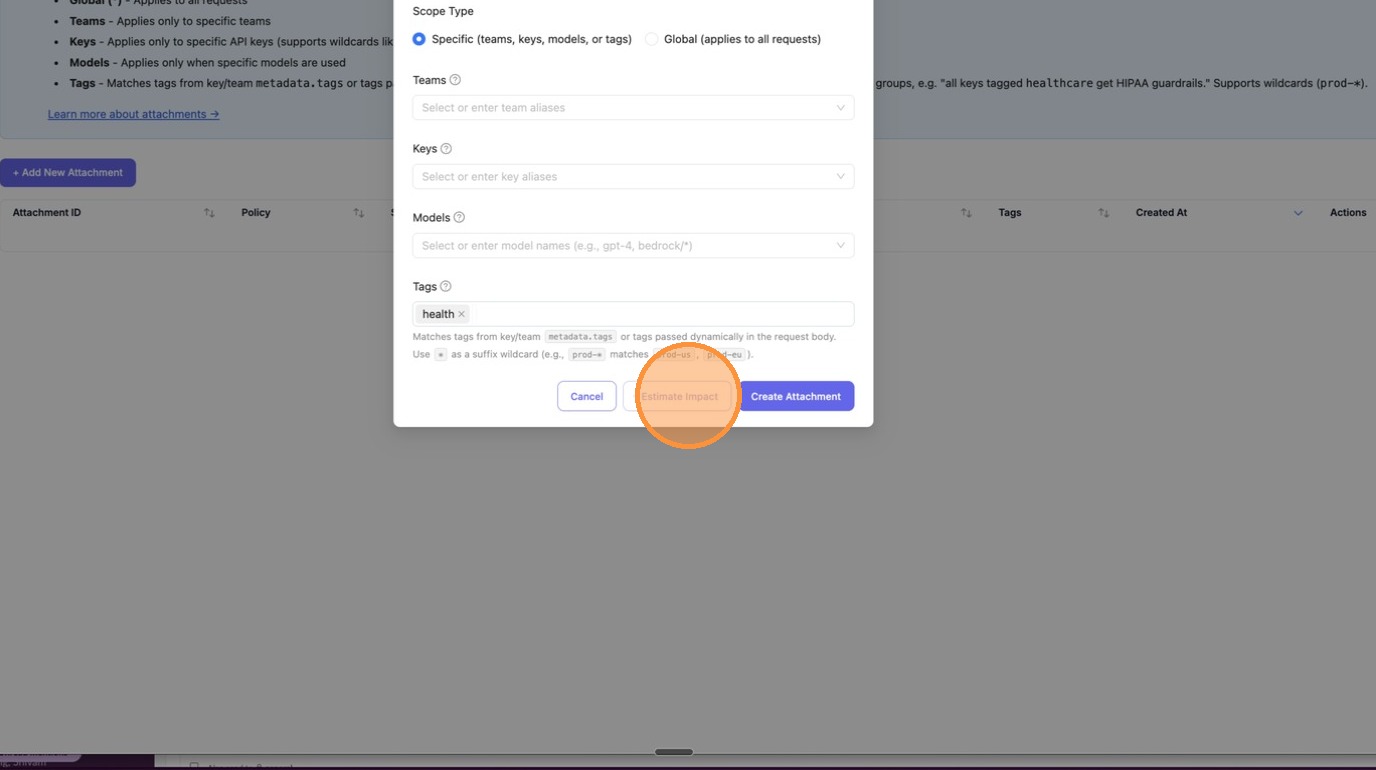
|
||||
|
||||
The **Impact Preview** appears inline, showing exactly how many keys and teams would be affected. In this example: "This attachment would affect **1 key** and **0 teams**", with the key alias `hi` listed.
|
||||
|
||||
|
||||
|
||||
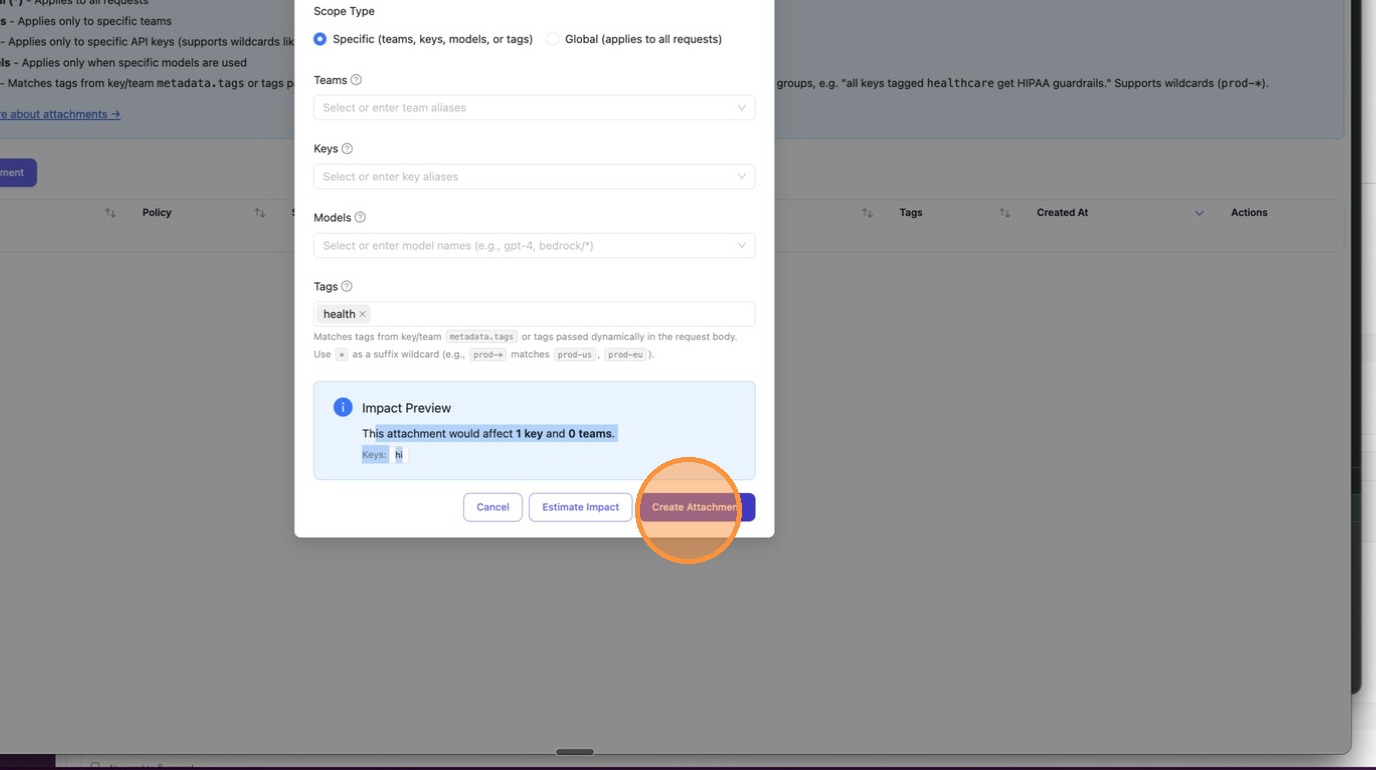
Once you're satisfied with the impact, click **Create Attachment** to save.
|
||||
|
||||
|
||||
|
||||
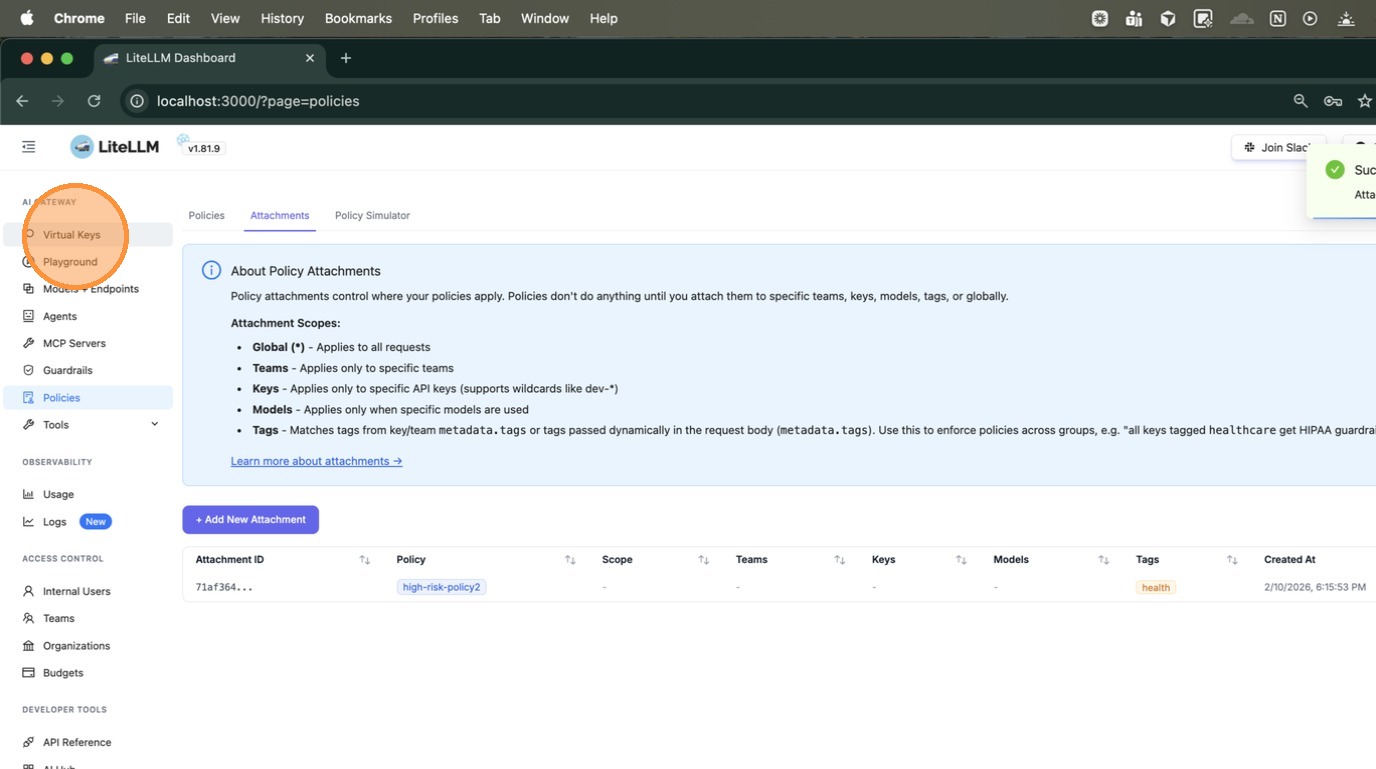
The attachment now appears in the table with the policy name `high-risk-policy2` and tag `health` visible.
|
||||
|
||||
|
||||
|
||||
## 4. Create a Key with the Tag
|
||||
|
||||
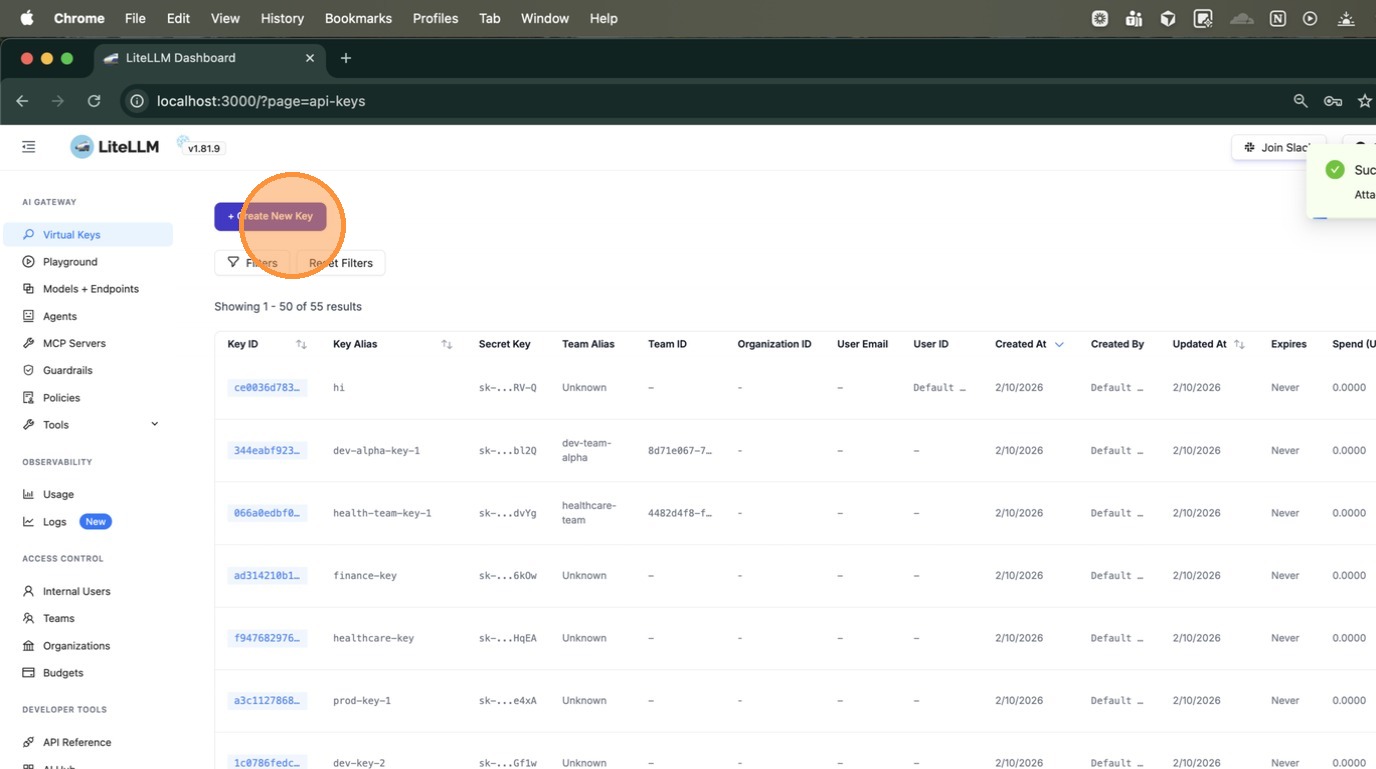
Navigate to **Virtual Keys** in the left sidebar. Click **+ Create New Key**.
|
||||
|
||||
|
||||
|
||||
Enter a key name and select a model. Then expand **Optional Settings** and scroll down to the **Tags** field.
|
||||
|
||||
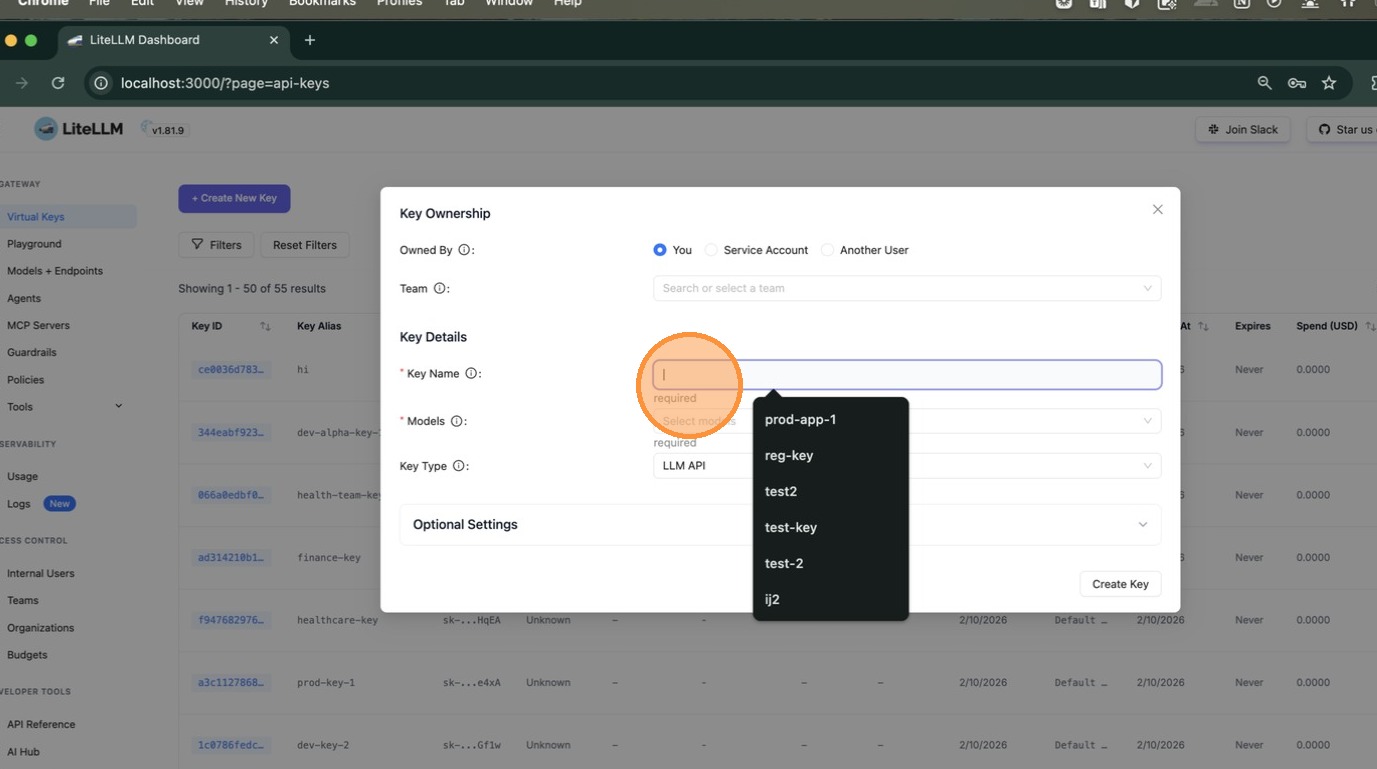
|
||||
|
||||
In the **Tags** field, type `health` and press Enter. This is the tag the policy engine will match against.
|
||||
|
||||
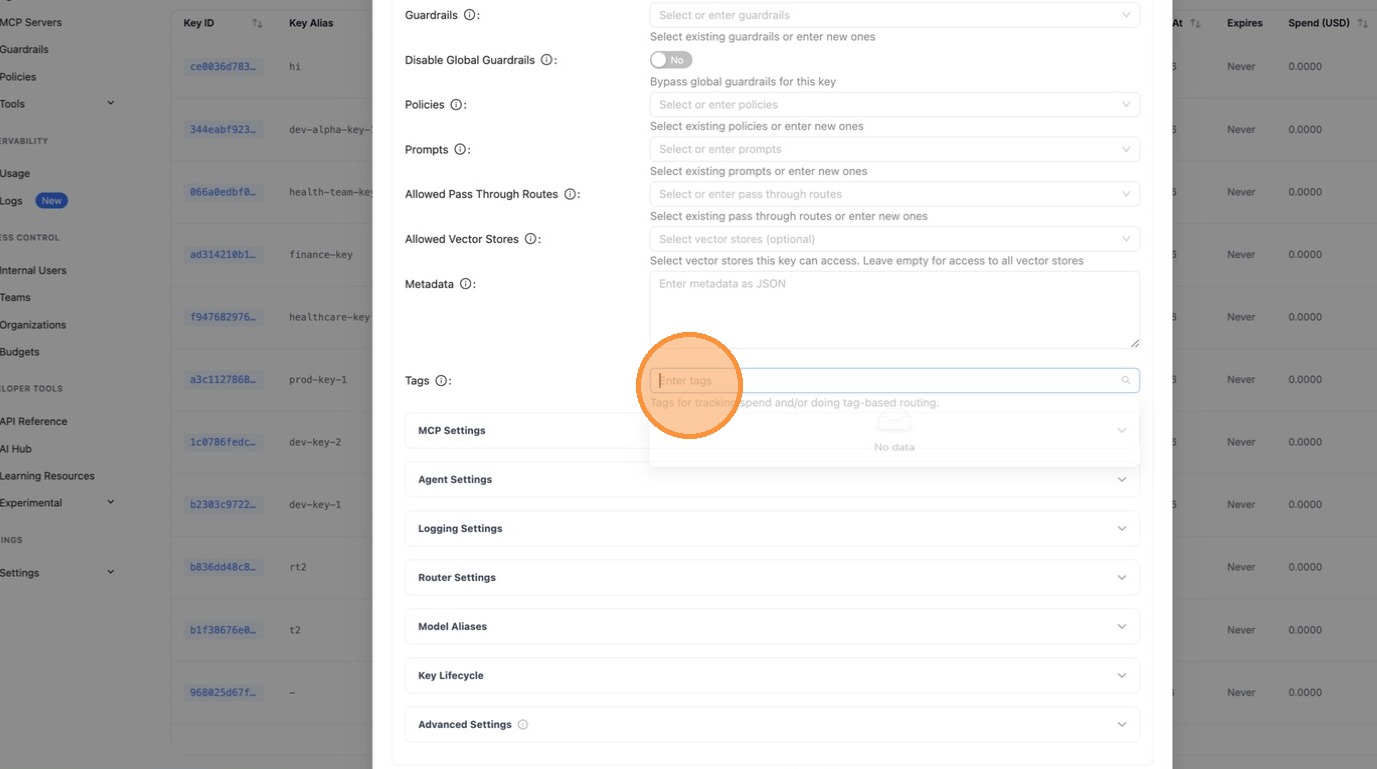
|
||||
|
||||
The tag `health` now appears as a chip in the Tags field. Confirm your settings look correct.
|
||||
|
||||
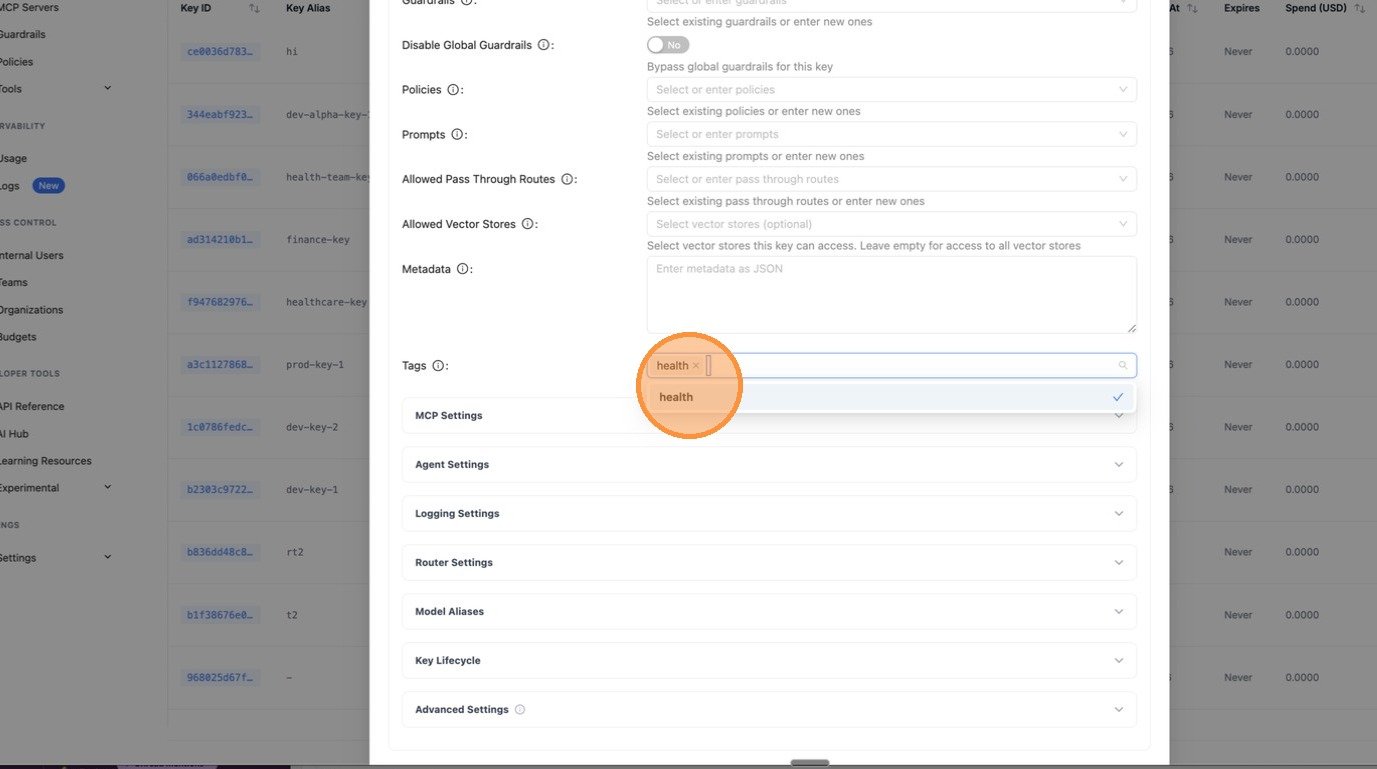
|
||||
|
||||
Click **Create Key** at the bottom of the form.
|
||||
|
||||
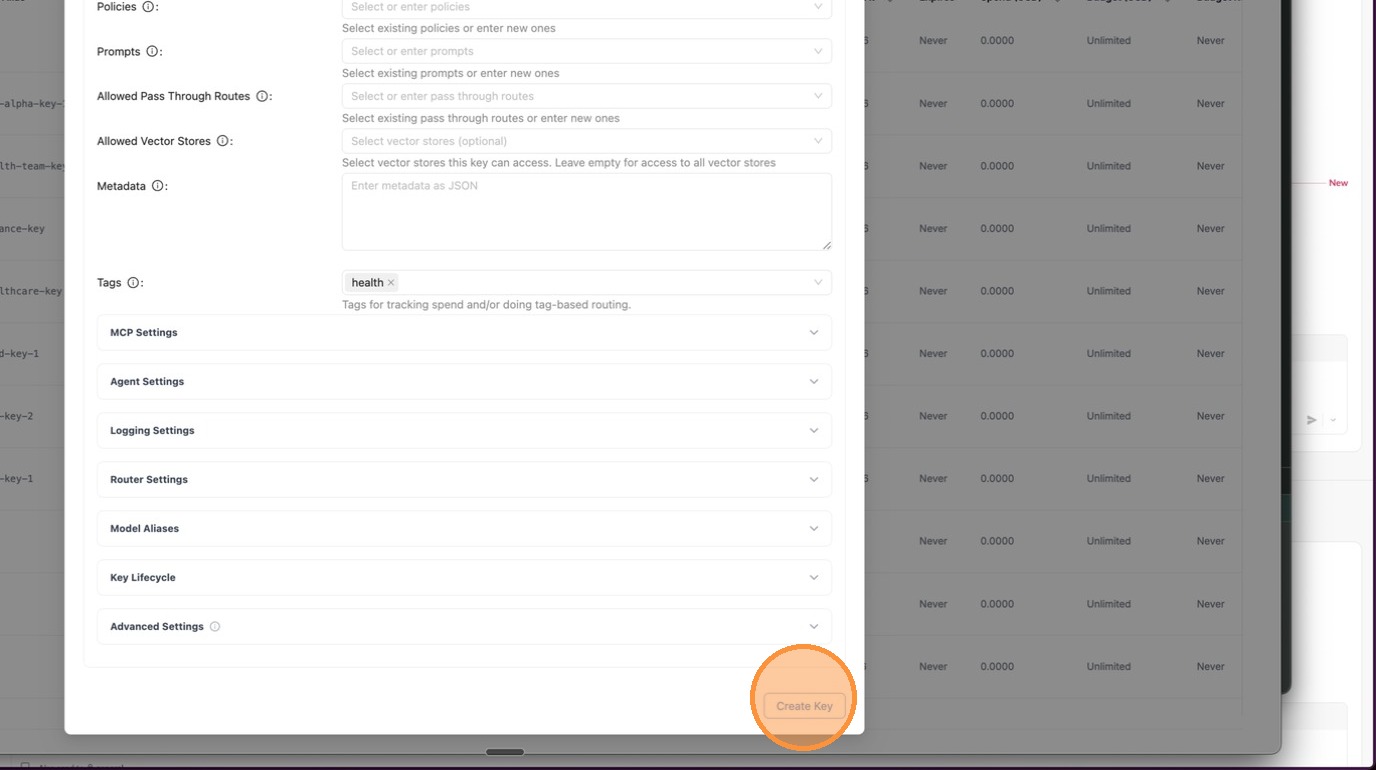
|
||||
|
||||
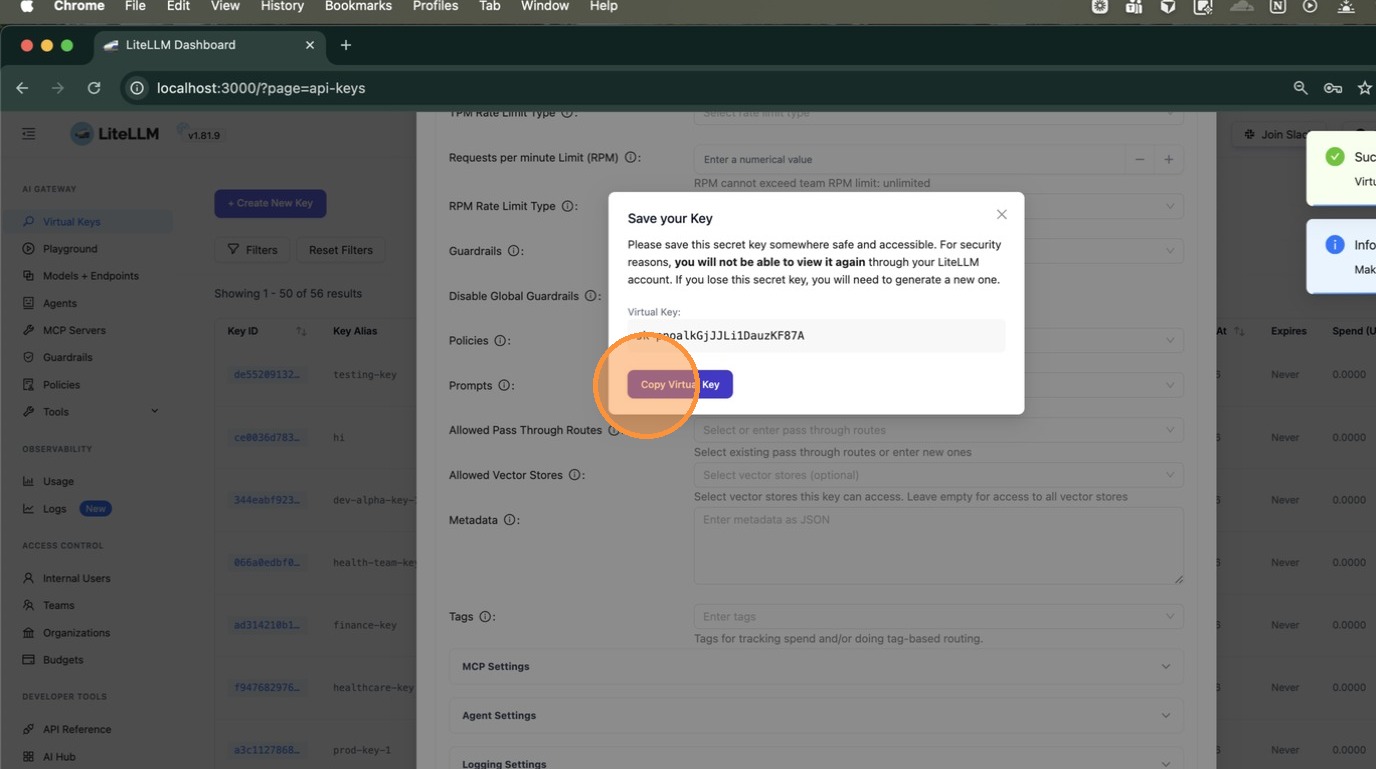
A dialog appears with your new virtual key. Click **Copy Virtual Key** — you'll need this to test in the next step.
|
||||
|
||||
|
||||
|
||||
## 5. Test the Key and Validate the Policy is Applied
|
||||
|
||||
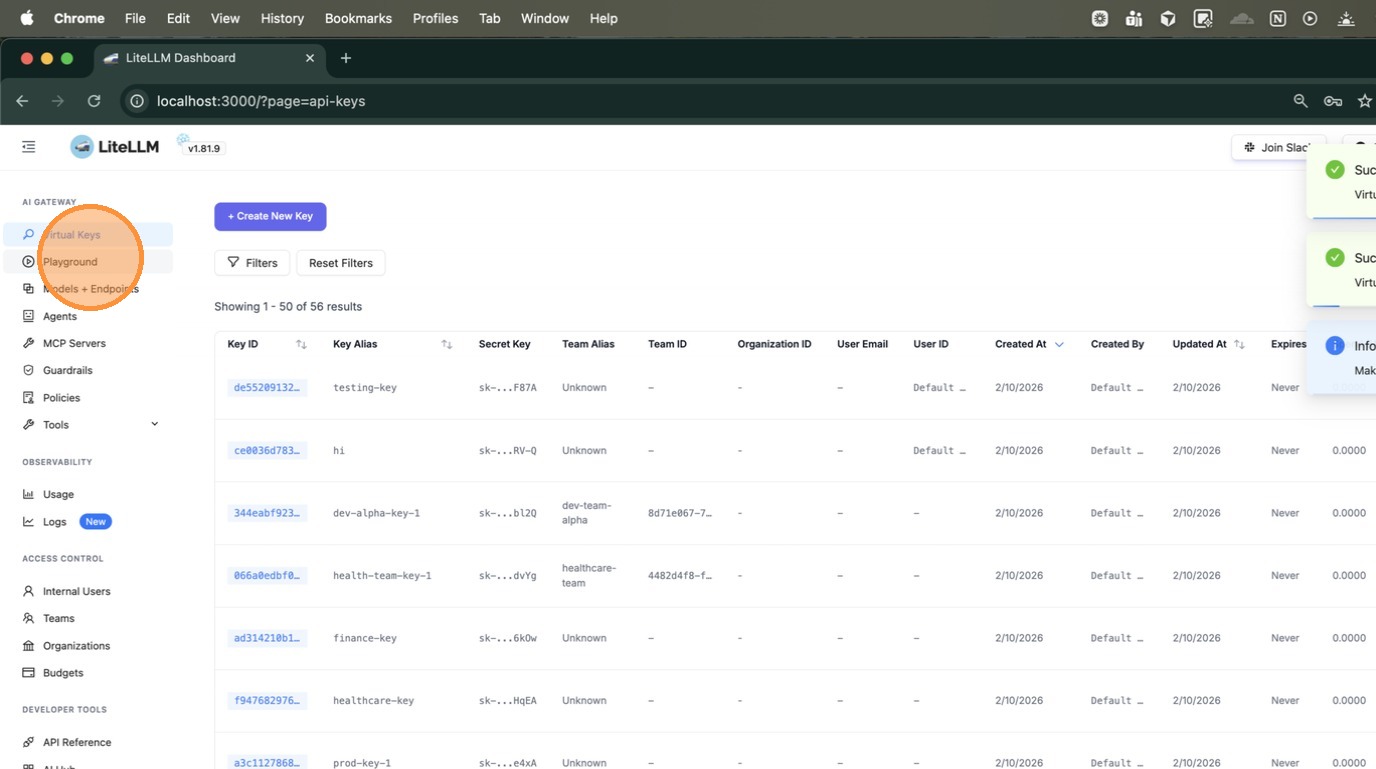
Navigate to **Playground** in the left sidebar to test the key interactively.
|
||||
|
||||
|
||||
|
||||
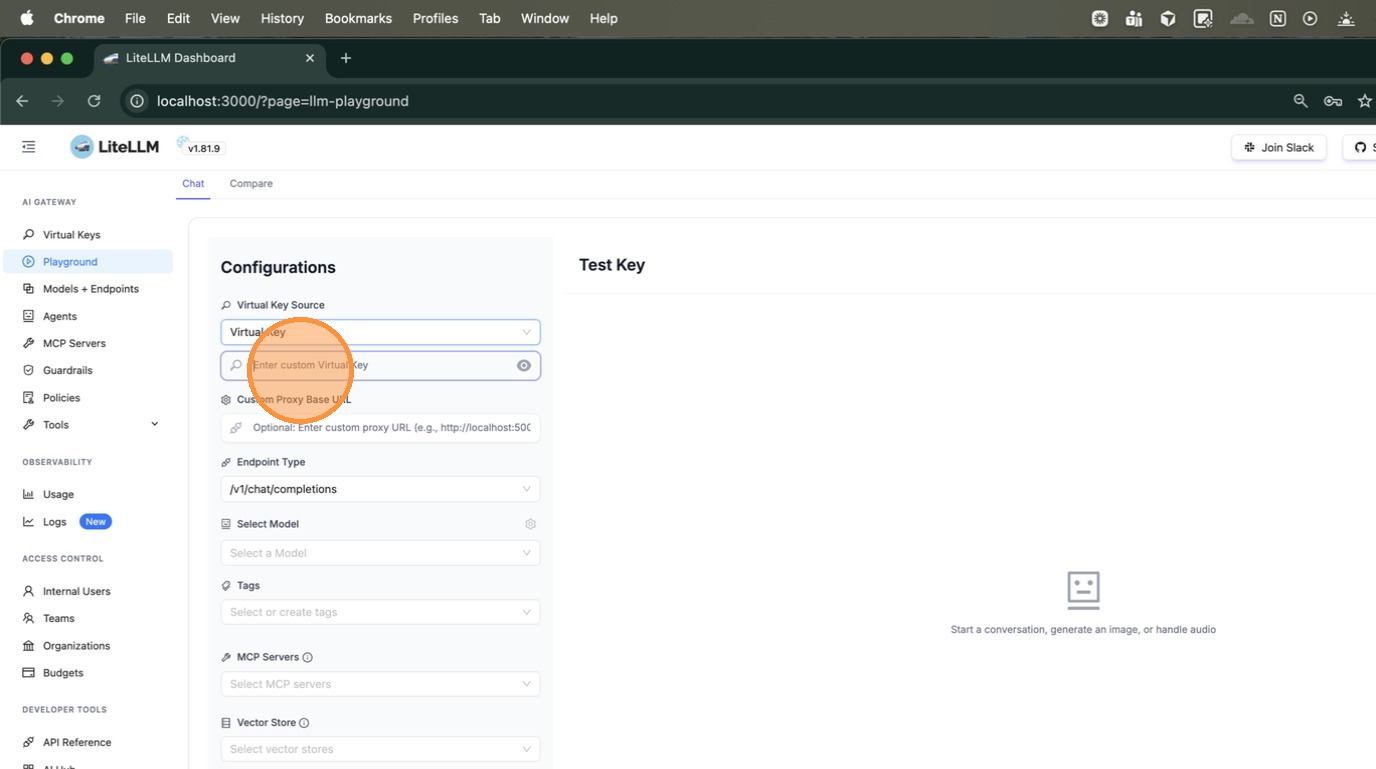
Under **Virtual Key Source**, select "Virtual Key" and paste the key you just copied into the input field.
|
||||
|
||||
|
||||
|
||||
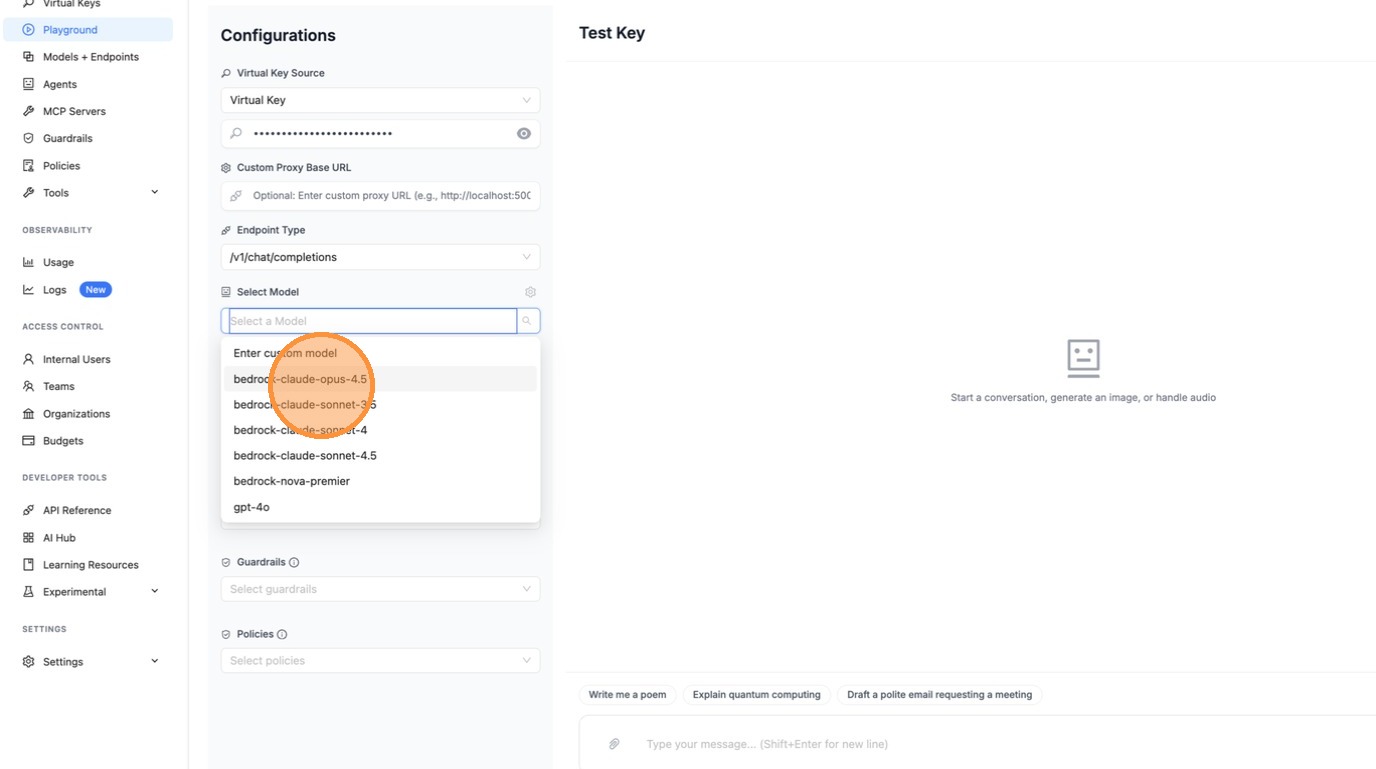
Select a model from the **Select Model** dropdown.
|
||||
|
||||
|
||||
|
||||
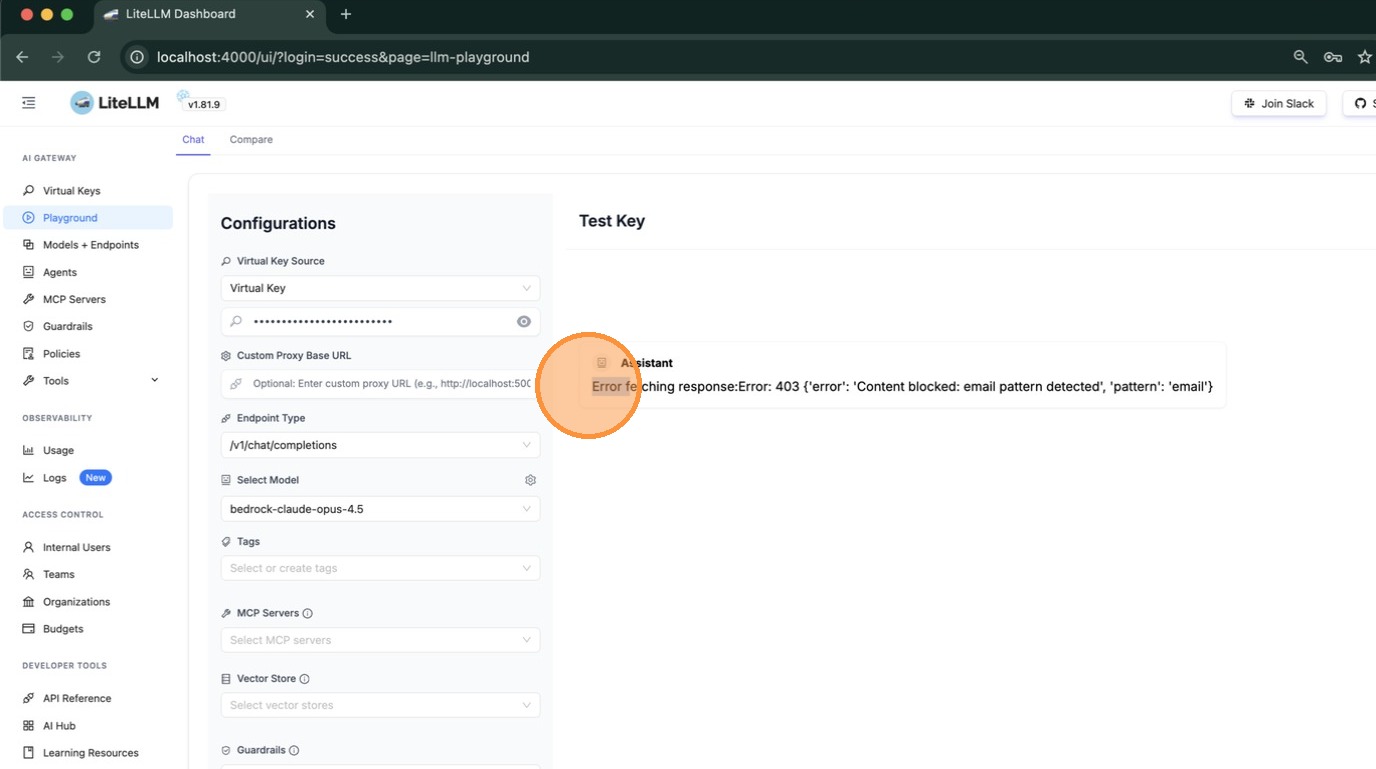
Type a message and press Enter. If a guardrail blocks the request, you'll see it in the response. In this example, the `testing-pl` guardrail detected an email pattern and returned a 403 error — confirming the policy is working.
|
||||
|
||||
|
||||
|
||||
**Using curl:**
|
||||
|
||||
You can also verify via the command line. The response headers confirm which policies and guardrails were applied:
|
||||
|
||||
```bash
|
||||
curl -v http://localhost:4000/chat/completions \
|
||||
-H "Authorization: Bearer <your-tagged-key>" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "gpt-4o",
|
||||
"messages": [{"role": "user", "content": "say hi"}]
|
||||
}'
|
||||
```
|
||||
|
||||
Check the response headers:
|
||||
|
||||
```
|
||||
x-litellm-applied-policies: high-risk-policy2
|
||||
x-litellm-applied-guardrails: pii-pre-guard,phi-pre-guard,testing-pl
|
||||
x-litellm-policy-sources: high-risk-policy2=tag:health
|
||||
```
|
||||
|
||||
| Header | What it tells you |
|
||||
|--------|-------------------|
|
||||
| `x-litellm-applied-policies` | Which policies matched this request |
|
||||
| `x-litellm-applied-guardrails` | Which guardrails actually ran |
|
||||
| `x-litellm-policy-sources` | **Why** each policy matched — `tag:health` confirms it was the tag |
|
||||
|
|
@ -1,8 +1,8 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Claude Code - Fixing Invalid Beta Header Errors
|
||||
# Claude Code - Managing Anthropic Beta Headers
|
||||
|
||||
When using Claude Code with LiteLLM and non-Anthropic providers (Bedrock, Azure AI, Vertex AI), you may encounter "invalid beta header" errors. This guide explains how to fix these errors locally or contribute a fix to LiteLLM.
|
||||
When using Claude Code with LiteLLM and non-Anthropic providers (Bedrock, Azure AI, Vertex AI), you need to ensure that only supported beta headers are sent to each provider. This guide explains how to add support for new beta headers or fix invalid beta header errors.
|
||||
|
||||
## What Are Beta Headers?
|
||||
|
||||
|
|
@ -12,7 +12,7 @@ Anthropic uses beta headers to enable experimental features in Claude. When you
|
|||
anthropic-beta: prompt-caching-scope-2026-01-05,advanced-tool-use-2025-11-20
|
||||
```
|
||||
|
||||
However, not all providers support all Anthropic beta features. When an unsupported beta header is sent to a provider, you'll see an error.
|
||||
However, not all providers support all Anthropic beta features. LiteLLM uses `anthropic_beta_headers_config.json` to manage which beta headers are supported by each provider.
|
||||
|
||||
## Common Error Message
|
||||
|
||||
|
|
@ -22,17 +22,22 @@ Error: The model returned the following errors: invalid beta flag
|
|||
|
||||
## How LiteLLM Handles Beta Headers
|
||||
|
||||
LiteLLM automatically filters out unsupported beta headers using a configuration file:
|
||||
LiteLLM uses a strict validation approach with a configuration file:
|
||||
|
||||
```
|
||||
litellm/litellm/anthropic_beta_headers_config.json
|
||||
```
|
||||
|
||||
This JSON file lists which beta headers are **unsupported** for each provider. Headers not in the unsupported list are passed through to the provider.
|
||||
This JSON file contains a **mapping** of beta headers for each provider:
|
||||
- **Keys**: Input beta header names (from Anthropic)
|
||||
- **Values**: Provider-specific header names (or `null` if unsupported)
|
||||
- **Validation**: Only headers present in the mapping with non-null values are forwarded
|
||||
|
||||
## Quick Fix: Update Config Locally
|
||||
This enforces stricter validation than just filtering unsupported headers - headers must be explicitly defined to be allowed.
|
||||
|
||||
If you encounter an invalid beta header error, you can fix it immediately by updating the config file locally.
|
||||
## Adding Support for a New Beta Header
|
||||
|
||||
When Anthropic releases a new beta feature, you need to add it to the configuration file for each provider.
|
||||
|
||||
### Step 1: Locate the Config File
|
||||
|
||||
|
|
@ -46,43 +51,47 @@ cd $(python -c "import litellm; import os; print(os.path.dirname(litellm.__file_
|
|||
# litellm/anthropic_beta_headers_config.json
|
||||
```
|
||||
|
||||
### Step 2: Add the Unsupported Header
|
||||
### Step 2: Add the New Beta Header
|
||||
|
||||
Open `anthropic_beta_headers_config.json` and add the problematic header to the appropriate provider's list:
|
||||
Open `anthropic_beta_headers_config.json` and add the new header to each provider's mapping:
|
||||
|
||||
```json title="anthropic_beta_headers_config.json"
|
||||
{
|
||||
"description": "Unsupported Anthropic beta headers for each provider. Headers listed here will be dropped. Headers not listed are passed through as-is.",
|
||||
"anthropic": [],
|
||||
"azure_ai": [],
|
||||
"bedrock_converse": [
|
||||
"prompt-caching-scope-2026-01-05",
|
||||
"bash_20250124",
|
||||
"bash_20241022",
|
||||
"text_editor_20250124",
|
||||
"text_editor_20241022",
|
||||
"compact-2026-01-12",
|
||||
"advanced-tool-use-2025-11-20",
|
||||
"web-fetch-2025-09-10",
|
||||
"code-execution-2025-08-25",
|
||||
"skills-2025-10-02",
|
||||
"files-api-2025-04-14"
|
||||
],
|
||||
"bedrock": [
|
||||
"advanced-tool-use-2025-11-20",
|
||||
"prompt-caching-scope-2026-01-05",
|
||||
"structured-outputs-2025-11-13",
|
||||
"web-fetch-2025-09-10",
|
||||
"code-execution-2025-08-25",
|
||||
"skills-2025-10-02",
|
||||
"files-api-2025-04-14"
|
||||
],
|
||||
"vertex_ai": [
|
||||
"prompt-caching-scope-2026-01-05"
|
||||
]
|
||||
"description": "Mapping of Anthropic beta headers for each provider. Keys are input header names, values are provider-specific header names (or null if unsupported). Only headers present in mapping keys with non-null values can be forwarded.",
|
||||
"anthropic": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"new-feature-2026-03-01": "new-feature-2026-03-01",
|
||||
...
|
||||
},
|
||||
"azure_ai": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"new-feature-2026-03-01": "new-feature-2026-03-01",
|
||||
...
|
||||
},
|
||||
"bedrock_converse": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"new-feature-2026-03-01": null,
|
||||
...
|
||||
},
|
||||
"bedrock": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"new-feature-2026-03-01": null,
|
||||
...
|
||||
},
|
||||
"vertex_ai": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"new-feature-2026-03-01": null,
|
||||
...
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Key Points:**
|
||||
- **Supported headers**: Set the value to the provider-specific header name (often the same as the key)
|
||||
- **Unsupported headers**: Set the value to `null`
|
||||
- **Header transformations**: Some providers use different header names (e.g., Bedrock maps `advanced-tool-use-2025-11-20` to `tool-search-tool-2025-10-19`)
|
||||
- **Alphabetical order**: Keep headers sorted alphabetically for maintainability
|
||||
|
||||
### Step 3: Restart Your Application
|
||||
|
||||
After updating the config file, restart your LiteLLM proxy or application:
|
||||
|
|
@ -97,9 +106,64 @@ litellm --config config.yaml
|
|||
|
||||
The updated configuration will be loaded automatically.
|
||||
|
||||
## Fixing Invalid Beta Header Errors
|
||||
|
||||
If you encounter an "invalid beta flag" error, it means a beta header is being sent that the provider doesn't support.
|
||||
|
||||
### Step 1: Identify the Problematic Header
|
||||
|
||||
Check your logs to see which header is causing the issue:
|
||||
|
||||
```bash
|
||||
Error: The model returned the following errors: invalid beta flag: new-feature-2026-03-01
|
||||
```
|
||||
|
||||
### Step 2: Update the Config
|
||||
|
||||
Set the header value to `null` for that provider:
|
||||
|
||||
```json title="anthropic_beta_headers_config.json"
|
||||
{
|
||||
"bedrock_converse": {
|
||||
"new-feature-2026-03-01": null
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Step 3: Restart and Test
|
||||
|
||||
Restart your application and verify the header is now filtered out.
|
||||
|
||||
## Contributing a Fix to LiteLLM
|
||||
|
||||
Help the community by contributing your fix! If your local changes work, please raise a PR with the addition of the header and we will merge it.
|
||||
Help the community by contributing your fix!
|
||||
|
||||
### What to Include in Your PR
|
||||
|
||||
1. **Update the config file**: Add the new beta header to `litellm/anthropic_beta_headers_config.json`
|
||||
2. **Test your changes**: Verify the header is correctly filtered/mapped for each provider
|
||||
3. **Documentation**: Include provider documentation links showing which headers are supported
|
||||
|
||||
### Example PR Description
|
||||
|
||||
```markdown
|
||||
## Add support for new-feature-2026-03-01 beta header
|
||||
|
||||
### Changes
|
||||
- Added `new-feature-2026-03-01` to anthropic_beta_headers_config.json
|
||||
- Set to `null` for bedrock_converse (unsupported)
|
||||
- Set to header name for anthropic, azure_ai (supported)
|
||||
|
||||
### Testing
|
||||
Tested with:
|
||||
- ✅ Anthropic: Header passed through correctly
|
||||
- ✅ Azure AI: Header passed through correctly
|
||||
- ✅ Bedrock Converse: Header filtered out (returns error without fix)
|
||||
|
||||
### References
|
||||
- Anthropic docs: [link]
|
||||
- AWS Bedrock docs: [link]
|
||||
```
|
||||
|
||||
|
||||
## How Beta Header Filtering Works
|
||||
|
|
@ -116,14 +180,51 @@ sequenceDiagram
|
|||
CC->>LP: Request with beta headers
|
||||
Note over CC,LP: anthropic-beta: header1,header2,header3
|
||||
|
||||
LP->>Config: Load unsupported headers for provider
|
||||
Config-->>LP: Returns unsupported list
|
||||
LP->>Config: Load header mapping for provider
|
||||
Config-->>LP: Returns mapping (header→value or null)
|
||||
|
||||
Note over LP: Filter headers:<br/>- Remove unsupported<br/>- Keep supported
|
||||
Note over LP: Validate & Transform:<br/>1. Check if header exists in mapping<br/>2. Filter out null values<br/>3. Map to provider-specific names
|
||||
|
||||
LP->>Provider: Request with filtered headers
|
||||
Note over LP,Provider: anthropic-beta: header2<br/>(header1, header3 removed)
|
||||
LP->>Provider: Request with filtered & mapped headers
|
||||
Note over LP,Provider: anthropic-beta: mapped-header2<br/>(header1, header3 filtered out)
|
||||
|
||||
Provider-->>LP: Success response
|
||||
LP-->>CC: Response
|
||||
```
|
||||
```
|
||||
|
||||
### Filtering Rules
|
||||
|
||||
1. **Header must exist in mapping**: Unknown headers are filtered out
|
||||
2. **Header must have non-null value**: Headers with `null` values are filtered out
|
||||
3. **Header transformation**: Headers are mapped to provider-specific names (e.g., `advanced-tool-use-2025-11-20` → `tool-search-tool-2025-10-19` for Bedrock)
|
||||
|
||||
### Example
|
||||
|
||||
Request with headers:
|
||||
```
|
||||
anthropic-beta: advanced-tool-use-2025-11-20,computer-use-2025-01-24,unknown-header
|
||||
```
|
||||
|
||||
For Bedrock Converse:
|
||||
- ✅ `computer-use-2025-01-24` → `computer-use-2025-01-24` (supported, passed through)
|
||||
- ❌ `advanced-tool-use-2025-11-20` → filtered out (null value in config)
|
||||
- ❌ `unknown-header` → filtered out (not in config)
|
||||
|
||||
Result sent to Bedrock:
|
||||
```
|
||||
anthropic-beta: computer-use-2025-01-24
|
||||
```
|
||||
|
||||
## Provider-Specific Notes
|
||||
|
||||
### Bedrock
|
||||
- Beta headers appear in both HTTP headers AND request body (`additionalModelRequestFields.anthropic_beta`)
|
||||
- Some headers are transformed (e.g., `advanced-tool-use` → `tool-search-tool`)
|
||||
|
||||
### Azure AI
|
||||
- Uses same header names as Anthropic
|
||||
- Some features not yet supported (check config for null values)
|
||||
|
||||
### Vertex AI
|
||||
- Some headers are transformed to match Vertex AI's implementation
|
||||
- Limited beta feature support compared to Anthropic
|
||||
BIN
docs/my-website/img/policy_team_attach.png
Normal file
BIN
docs/my-website/img/policy_team_attach.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 225 KiB |
BIN
docs/my-website/img/policy_test_matching.png
Normal file
BIN
docs/my-website/img/policy_test_matching.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 200 KiB |
|
|
@ -42,49 +42,62 @@ const sidebars = {
|
|||
label: "Guardrails",
|
||||
items: [
|
||||
"proxy/guardrails/quick_start",
|
||||
"proxy/guardrails/guardrail_policies",
|
||||
"proxy/guardrails/guardrail_load_balancing",
|
||||
"proxy/guardrails/test_playground",
|
||||
"proxy/guardrails/litellm_content_filter",
|
||||
{
|
||||
type: "category",
|
||||
"label": "Contributing to Guardrails",
|
||||
label: "Providers",
|
||||
items: [
|
||||
...[
|
||||
"proxy/guardrails/qualifire",
|
||||
"proxy/guardrails/aim_security",
|
||||
"proxy/guardrails/onyx_security",
|
||||
"proxy/guardrails/aporia_api",
|
||||
"proxy/guardrails/azure_content_guardrail",
|
||||
"proxy/guardrails/bedrock",
|
||||
"proxy/guardrails/enkryptai",
|
||||
"proxy/guardrails/ibm_guardrails",
|
||||
"proxy/guardrails/grayswan",
|
||||
"proxy/guardrails/hiddenlayer",
|
||||
"proxy/guardrails/lasso_security",
|
||||
"proxy/guardrails/guardrails_ai",
|
||||
"proxy/guardrails/lakera_ai",
|
||||
"proxy/guardrails/model_armor",
|
||||
"proxy/guardrails/noma_security",
|
||||
"proxy/guardrails/dynamoai",
|
||||
"proxy/guardrails/openai_moderation",
|
||||
"proxy/guardrails/pangea",
|
||||
"proxy/guardrails/pillar_security",
|
||||
"proxy/guardrails/pii_masking_v2",
|
||||
"proxy/guardrails/panw_prisma_airs",
|
||||
"proxy/guardrails/secret_detection",
|
||||
"proxy/guardrails/custom_guardrail",
|
||||
"proxy/guardrails/custom_code_guardrail",
|
||||
"proxy/guardrails/prompt_injection",
|
||||
"proxy/guardrails/tool_permission",
|
||||
"proxy/guardrails/zscaler_ai_guard",
|
||||
"proxy/guardrails/javelin"
|
||||
].sort(),
|
||||
],
|
||||
},
|
||||
{
|
||||
type: "category",
|
||||
label: "Contributing to Guardrails",
|
||||
items: [
|
||||
"adding_provider/generic_guardrail_api",
|
||||
"adding_provider/simple_guardrail_tutorial",
|
||||
"adding_provider/adding_guardrail_support",
|
||||
]
|
||||
},
|
||||
"proxy/guardrails/test_playground",
|
||||
"proxy/guardrails/litellm_content_filter",
|
||||
...[
|
||||
"proxy/guardrails/qualifire",
|
||||
"proxy/guardrails/aim_security",
|
||||
"proxy/guardrails/onyx_security",
|
||||
"proxy/guardrails/aporia_api",
|
||||
"proxy/guardrails/azure_content_guardrail",
|
||||
"proxy/guardrails/bedrock",
|
||||
"proxy/guardrails/enkryptai",
|
||||
"proxy/guardrails/ibm_guardrails",
|
||||
"proxy/guardrails/grayswan",
|
||||
"proxy/guardrails/hiddenlayer",
|
||||
"proxy/guardrails/lasso_security",
|
||||
"proxy/guardrails/guardrails_ai",
|
||||
"proxy/guardrails/lakera_ai",
|
||||
"proxy/guardrails/model_armor",
|
||||
"proxy/guardrails/noma_security",
|
||||
"proxy/guardrails/dynamoai",
|
||||
"proxy/guardrails/openai_moderation",
|
||||
"proxy/guardrails/pangea",
|
||||
"proxy/guardrails/pillar_security",
|
||||
"proxy/guardrails/pii_masking_v2",
|
||||
"proxy/guardrails/panw_prisma_airs",
|
||||
"proxy/guardrails/secret_detection",
|
||||
"proxy/guardrails/custom_guardrail",
|
||||
"proxy/guardrails/custom_code_guardrail",
|
||||
"proxy/guardrails/prompt_injection",
|
||||
"proxy/guardrails/tool_permission",
|
||||
"proxy/guardrails/zscaler_ai_guard",
|
||||
"proxy/guardrails/javelin"
|
||||
].sort(),
|
||||
],
|
||||
},
|
||||
{
|
||||
type: "category",
|
||||
label: "Policies",
|
||||
items: [
|
||||
"proxy/guardrails/guardrail_policies",
|
||||
"proxy/guardrails/policy_tags",
|
||||
],
|
||||
},
|
||||
{
|
||||
|
|
@ -396,6 +409,16 @@ const sidebars = {
|
|||
],
|
||||
},
|
||||
"proxy/caching",
|
||||
{
|
||||
type: "link",
|
||||
label: "Guardrails",
|
||||
href: "https://docs.litellm.ai/docs/proxy/guardrails/quick_start",
|
||||
},
|
||||
{
|
||||
type: "link",
|
||||
label: "Policies",
|
||||
href: "https://docs.litellm.ai/docs/proxy/guardrails/guardrail_policies",
|
||||
},
|
||||
{
|
||||
type: "category",
|
||||
label: "Create Custom Plugins",
|
||||
|
|
|
|||
|
|
@ -914,6 +914,7 @@ model LiteLLM_PolicyAttachmentTable {
|
|||
teams String[] @default([]) // Team aliases or patterns
|
||||
keys String[] @default([]) // Key aliases or patterns
|
||||
models String[] @default([]) // Model names or patterns
|
||||
tags String[] @default([]) // Tag patterns (e.g., ["healthcare", "prod-*"])
|
||||
created_at DateTime @default(now())
|
||||
created_by String?
|
||||
updated_at DateTime @default(now()) @updatedAt
|
||||
|
|
|
|||
|
|
@ -1155,6 +1155,7 @@ from .exceptions import (
|
|||
BadRequestError,
|
||||
ImageFetchError,
|
||||
NotFoundError,
|
||||
PermissionDeniedError,
|
||||
RateLimitError,
|
||||
ServiceUnavailableError,
|
||||
BadGatewayError,
|
||||
|
|
|
|||
|
|
@ -1,33 +1,151 @@
|
|||
{
|
||||
"description": "Unsupported Anthropic beta headers for each provider. Headers listed here will be dropped. Headers not listed are passed through as-is.",
|
||||
"anthropic": [],
|
||||
"azure_ai": [],
|
||||
"bedrock_converse": [
|
||||
"prompt-caching-scope-2026-01-05",
|
||||
"bash_20250124",
|
||||
"bash_20241022",
|
||||
"text_editor_20250124",
|
||||
"text_editor_20241022",
|
||||
"compact-2026-01-12",
|
||||
"advanced-tool-use-2025-11-20",
|
||||
"web-fetch-2025-09-10",
|
||||
"code-execution-2025-08-25",
|
||||
"skills-2025-10-02",
|
||||
"files-api-2025-04-14",
|
||||
"fast-mode-2026-02-01"
|
||||
],
|
||||
"bedrock": [
|
||||
"advanced-tool-use-2025-11-20",
|
||||
"prompt-caching-scope-2026-01-05",
|
||||
"structured-outputs-2025-11-13",
|
||||
"web-fetch-2025-09-10",
|
||||
"code-execution-2025-08-25",
|
||||
"skills-2025-10-02",
|
||||
"files-api-2025-04-14",
|
||||
"fast-mode-2026-02-01",
|
||||
"mcp-servers-2025-12-04"
|
||||
],
|
||||
"vertex_ai": [
|
||||
"prompt-caching-scope-2026-01-05"
|
||||
]
|
||||
}
|
||||
"description": "Mapping of Anthropic beta headers for each provider. Keys are input header names, values are provider-specific header names (or null if unsupported). Only headers present in mapping keys with non-null values can be forwarded.",
|
||||
"anthropic": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"bash_20241022": "bash_20241022",
|
||||
"bash_20250124": "bash_20250124",
|
||||
"code-execution-2025-08-25": "code-execution-2025-08-25",
|
||||
"compact-2026-01-12": "compact-2026-01-12",
|
||||
"computer-use-2025-01-24": "computer-use-2025-01-24",
|
||||
"computer-use-2025-11-24": "computer-use-2025-11-24",
|
||||
"context-1m-2025-08-07": "context-1m-2025-08-07",
|
||||
"context-management-2025-06-27": "context-management-2025-06-27",
|
||||
"effort-2025-11-24": "effort-2025-11-24",
|
||||
"fast-mode-2026-02-01": "fast-mode-2026-02-01",
|
||||
"files-api-2025-04-14": "files-api-2025-04-14",
|
||||
"structured-output-2024-03-01": "structured-output-2024-03-01",
|
||||
"fine-grained-tool-streaming-2025-05-14": "fine-grained-tool-streaming-2025-05-14",
|
||||
"interleaved-thinking-2025-05-14": "interleaved-thinking-2025-05-14",
|
||||
"mcp-client-2025-11-20": "mcp-client-2025-11-20",
|
||||
"mcp-client-2025-04-04": "mcp-client-2025-04-04",
|
||||
"mcp-servers-2025-12-04": "mcp-servers-2025-12-04",
|
||||
"output-128k-2025-02-19": "output-128k-2025-02-19",
|
||||
"prompt-caching-scope-2026-01-05": "prompt-caching-scope-2026-01-05",
|
||||
"skills-2025-10-02": "skills-2025-10-02",
|
||||
"structured-outputs-2025-11-13": "structured-outputs-2025-11-13",
|
||||
"text_editor_20241022": "text_editor_20241022",
|
||||
"text_editor_20250124": "text_editor_20250124",
|
||||
"token-efficient-tools-2025-02-19": "token-efficient-tools-2025-02-19",
|
||||
"web-fetch-2025-09-10": "web-fetch-2025-09-10",
|
||||
"web-search-2025-03-05": "web-search-2025-03-05"
|
||||
},
|
||||
"azure_ai": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"bash_20241022": "bash_20241022",
|
||||
"bash_20250124": "bash_20250124",
|
||||
"code-execution-2025-08-25": "code-execution-2025-08-25",
|
||||
"compact-2026-01-12": null,
|
||||
"computer-use-2025-01-24": "computer-use-2025-01-24",
|
||||
"computer-use-2025-11-24": "computer-use-2025-11-24",
|
||||
"context-1m-2025-08-07": "context-1m-2025-08-07",
|
||||
"context-management-2025-06-27": "context-management-2025-06-27",
|
||||
"effort-2025-11-24": "effort-2025-11-24",
|
||||
"fast-mode-2026-02-01": null,
|
||||
"files-api-2025-04-14": "files-api-2025-04-14",
|
||||
"fine-grained-tool-streaming-2025-05-14": null,
|
||||
"interleaved-thinking-2025-05-14": "interleaved-thinking-2025-05-14",
|
||||
"mcp-client-2025-11-20": "mcp-client-2025-11-20",
|
||||
"mcp-client-2025-04-04": "mcp-client-2025-04-04",
|
||||
"mcp-servers-2025-12-04": "mcp-servers-2025-12-04",
|
||||
"output-128k-2025-02-19": null,
|
||||
"structured-output-2024-03-01": null,
|
||||
"prompt-caching-scope-2026-01-05": "prompt-caching-scope-2026-01-05",
|
||||
"skills-2025-10-02": "skills-2025-10-02",
|
||||
"structured-outputs-2025-11-13": "structured-outputs-2025-11-13",
|
||||
"text_editor_20241022": null,
|
||||
"text_editor_20250124": null,
|
||||
"token-efficient-tools-2025-02-19": null,
|
||||
"web-fetch-2025-09-10": "web-fetch-2025-09-10",
|
||||
"web-search-2025-03-05": "web-search-2025-03-05"
|
||||
},
|
||||
"bedrock_converse": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"bash_20241022": null,
|
||||
"bash_20250124": null,
|
||||
"code-execution-2025-08-25": null,
|
||||
"compact-2026-01-12": null,
|
||||
"computer-use-2025-01-24": "computer-use-2025-01-24",
|
||||
"computer-use-2025-11-24": "computer-use-2025-11-24",
|
||||
"context-1m-2025-08-07": null,
|
||||
"context-management-2025-06-27": "context-management-2025-06-27",
|
||||
"effort-2025-11-24": null,
|
||||
"fast-mode-2026-02-01": null,
|
||||
"files-api-2025-04-14": null,
|
||||
"fine-grained-tool-streaming-2025-05-14": null,
|
||||
"interleaved-thinking-2025-05-14": "interleaved-thinking-2025-05-14",
|
||||
"mcp-client-2025-11-20": null,
|
||||
"mcp-client-2025-04-04": null,
|
||||
"mcp-servers-2025-12-04": null,
|
||||
"output-128k-2025-02-19": null,
|
||||
"structured-output-2024-03-01": null,
|
||||
"prompt-caching-scope-2026-01-05": null,
|
||||
"skills-2025-10-02": null,
|
||||
"structured-outputs-2025-11-13": "structured-outputs-2025-11-13",
|
||||
"text_editor_20241022": null,
|
||||
"text_editor_20250124": null,
|
||||
"token-efficient-tools-2025-02-19": null,
|
||||
"tool-search-tool-2025-10-19": "tool-search-tool-2025-10-19",
|
||||
"web-fetch-2025-09-10": null,
|
||||
"web-search-2025-03-05": null
|
||||
},
|
||||
"bedrock": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"bash_20241022": null,
|
||||
"bash_20250124": null,
|
||||
"code-execution-2025-08-25": null,
|
||||
"compact-2026-01-12": "compact-2026-01-12",
|
||||
"computer-use-2025-01-24": "computer-use-2025-01-24",
|
||||
"computer-use-2025-11-24": "computer-use-2025-11-24",
|
||||
"context-1m-2025-08-07": "context-1m-2025-08-07",
|
||||
"context-management-2025-06-27": "context-management-2025-06-27",
|
||||
"effort-2025-11-24": null,
|
||||
"fast-mode-2026-02-01": null,
|
||||
"files-api-2025-04-14": null,
|
||||
"fine-grained-tool-streaming-2025-05-14": null,
|
||||
"interleaved-thinking-2025-05-14": "interleaved-thinking-2025-05-14",
|
||||
"mcp-client-2025-11-20": null,
|
||||
"mcp-client-2025-04-04": null,
|
||||
"mcp-servers-2025-12-04": null,
|
||||
"output-128k-2025-02-19": null,
|
||||
"structured-output-2024-03-01": null,
|
||||
"prompt-caching-scope-2026-01-05": null,
|
||||
"skills-2025-10-02": null,
|
||||
"structured-outputs-2025-11-13": null,
|
||||
"text_editor_20241022": null,
|
||||
"text_editor_20250124": null,
|
||||
"token-efficient-tools-2025-02-19": null,
|
||||
"tool-search-tool-2025-10-19": "tool-search-tool-2025-10-19",
|
||||
"web-fetch-2025-09-10": null,
|
||||
"web-search-2025-03-05": null
|
||||
},
|
||||
"vertex_ai": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"bash_20241022": null,
|
||||
"bash_20250124": null,
|
||||
"code-execution-2025-08-25": null,
|
||||
"compact-2026-01-12": null,
|
||||
"computer-use-2025-01-24": "computer-use-2025-01-24",
|
||||
"computer-use-2025-11-24": "computer-use-2025-11-24",
|
||||
"context-1m-2025-08-07": null,
|
||||
"context-management-2025-06-27": "context-management-2025-06-27",
|
||||
"effort-2025-11-24": null,
|
||||
"fast-mode-2026-02-01": null,
|
||||
"files-api-2025-04-14": null,
|
||||
"fine-grained-tool-streaming-2025-05-14": null,
|
||||
"interleaved-thinking-2025-05-14": "interleaved-thinking-2025-05-14",
|
||||
"mcp-client-2025-11-20": null,
|
||||
"mcp-client-2025-04-04": null,
|
||||
"mcp-servers-2025-12-04": null,
|
||||
"output-128k-2025-02-19": null,
|
||||
"structured-output-2024-03-01": null,
|
||||
"prompt-caching-scope-2026-01-05": null,
|
||||
"skills-2025-10-02": null,
|
||||
"structured-outputs-2025-11-13": null,
|
||||
"text_editor_20241022": null,
|
||||
"text_editor_20250124": null,
|
||||
"token-efficient-tools-2025-02-19": null,
|
||||
"tool-search-tool-2025-10-19": "tool-search-tool-2025-10-19",
|
||||
"web-fetch-2025-09-10": null,
|
||||
"web-search-2025-03-05": "web-search-2025-03-05"
|
||||
}
|
||||
}
|
||||
|
|
@ -2,14 +2,15 @@
|
|||
Centralized manager for Anthropic beta headers across different providers.
|
||||
|
||||
This module provides utilities to:
|
||||
1. Load beta header configuration from JSON (lists unsupported headers per provider)
|
||||
2. Filter out unsupported beta headers
|
||||
1. Load beta header configuration from JSON (mapping of supported headers per provider)
|
||||
2. Filter and map beta headers based on provider support
|
||||
3. Handle provider-specific header name mappings (e.g., advanced-tool-use -> tool-search-tool)
|
||||
|
||||
Design:
|
||||
- JSON config lists UNSUPPORTED headers for each provider
|
||||
- Headers not in the unsupported list are passed through
|
||||
- Header mappings allow renaming headers for specific providers
|
||||
- JSON config contains mapping of beta headers for each provider
|
||||
- Keys are input header names, values are provider-specific header names (or null if unsupported)
|
||||
- Only headers present in mapping keys with non-null values can be forwarded
|
||||
- This enforces stricter validation than the previous unsupported list approach
|
||||
"""
|
||||
|
||||
import json
|
||||
|
|
@ -47,13 +48,13 @@ def _load_beta_headers_config() -> Dict:
|
|||
return _BETA_HEADERS_CONFIG
|
||||
except Exception as e:
|
||||
verbose_logger.error(f"Failed to load beta headers config: {e}")
|
||||
# Return empty config as fallback
|
||||
# Return empty config as fallback (empty mappings)
|
||||
return {
|
||||
"anthropic": [],
|
||||
"azure_ai": [],
|
||||
"bedrock": [],
|
||||
"bedrock_converse": [],
|
||||
"vertex_ai": []
|
||||
"anthropic": {},
|
||||
"azure_ai": {},
|
||||
"bedrock": {},
|
||||
"bedrock_converse": {},
|
||||
"vertex_ai": {}
|
||||
}
|
||||
|
||||
|
||||
|
|
@ -77,21 +78,19 @@ def filter_and_transform_beta_headers(
|
|||
provider: str,
|
||||
) -> List[str]:
|
||||
"""
|
||||
Filter beta headers based on provider's unsupported list.
|
||||
Filter and transform beta headers based on provider's mapping configuration.
|
||||
|
||||
This function:
|
||||
1. Removes headers that are in the provider's unsupported list
|
||||
2. Passes through all other headers as-is
|
||||
|
||||
Note: Header transformations/mappings (e.g., advanced-tool-use -> tool-search-tool)
|
||||
are handled in each provider's transformation code, not here.
|
||||
1. Only allows headers that are present in the provider's mapping keys
|
||||
2. Filters out headers with null values (unsupported)
|
||||
3. Maps headers to provider-specific names (e.g., advanced-tool-use -> tool-search-tool)
|
||||
|
||||
Args:
|
||||
beta_headers: List of Anthropic beta header values
|
||||
provider: Provider name (e.g., "anthropic", "bedrock", "vertex_ai")
|
||||
|
||||
Returns:
|
||||
List of filtered beta headers for the provider
|
||||
List of filtered and transformed beta headers for the provider
|
||||
"""
|
||||
if not beta_headers:
|
||||
return []
|
||||
|
|
@ -99,23 +98,33 @@ def filter_and_transform_beta_headers(
|
|||
config = _load_beta_headers_config()
|
||||
provider = get_provider_name(provider)
|
||||
|
||||
# Get unsupported headers for this provider
|
||||
unsupported_headers = set(config.get(provider, []))
|
||||
# Get the header mapping for this provider
|
||||
provider_mapping = config.get(provider, {})
|
||||
|
||||
filtered_headers: Set[str] = set()
|
||||
|
||||
for header in beta_headers:
|
||||
header = header.strip()
|
||||
|
||||
# Skip if header is unsupported
|
||||
if header in unsupported_headers:
|
||||
# Check if header is in the mapping
|
||||
if header not in provider_mapping:
|
||||
verbose_logger.debug(
|
||||
f"Dropping unknown beta header '{header}' for provider '{provider}' (not in mapping)"
|
||||
)
|
||||
continue
|
||||
|
||||
# Get the mapped header value
|
||||
mapped_header = provider_mapping[header]
|
||||
|
||||
# Skip if header is unsupported (null value)
|
||||
if mapped_header is None:
|
||||
verbose_logger.debug(
|
||||
f"Dropping unsupported beta header '{header}' for provider '{provider}'"
|
||||
)
|
||||
continue
|
||||
|
||||
# Pass through as-is
|
||||
filtered_headers.add(header)
|
||||
# Add the mapped header
|
||||
filtered_headers.add(mapped_header)
|
||||
|
||||
return sorted(list(filtered_headers))
|
||||
|
||||
|
|
@ -132,12 +141,14 @@ def is_beta_header_supported(
|
|||
provider: Provider name
|
||||
|
||||
Returns:
|
||||
True if the header is supported (not in unsupported list), False otherwise
|
||||
True if the header is in the mapping with a non-null value, False otherwise
|
||||
"""
|
||||
config = _load_beta_headers_config()
|
||||
provider = get_provider_name(provider)
|
||||
unsupported_headers = set(config.get(provider, []))
|
||||
return beta_header not in unsupported_headers
|
||||
provider_mapping = config.get(provider, {})
|
||||
|
||||
# Header is supported if it's in the mapping and has a non-null value
|
||||
return beta_header in provider_mapping and provider_mapping[beta_header] is not None
|
||||
|
||||
|
||||
def get_provider_beta_header(
|
||||
|
|
@ -145,27 +156,29 @@ def get_provider_beta_header(
|
|||
provider: str,
|
||||
) -> Optional[str]:
|
||||
"""
|
||||
Check if a beta header is supported by a provider.
|
||||
Get the provider-specific beta header name for a given Anthropic beta header.
|
||||
|
||||
Note: This does NOT handle header transformations/mappings.
|
||||
Those are handled in each provider's transformation code.
|
||||
This function handles header transformations/mappings (e.g., advanced-tool-use -> tool-search-tool).
|
||||
|
||||
Args:
|
||||
anthropic_beta_header: The Anthropic beta header value
|
||||
provider: Provider name
|
||||
|
||||
Returns:
|
||||
The original header if supported, or None if unsupported
|
||||
The provider-specific header name if supported, or None if unsupported/unknown
|
||||
"""
|
||||
config = _load_beta_headers_config()
|
||||
provider = get_provider_name(provider)
|
||||
|
||||
# Check if unsupported
|
||||
unsupported_headers = set(config.get(provider, []))
|
||||
if anthropic_beta_header in unsupported_headers:
|
||||
# Get the header mapping for this provider
|
||||
provider_mapping = config.get(provider, {})
|
||||
|
||||
# Check if header is in the mapping
|
||||
if anthropic_beta_header not in provider_mapping:
|
||||
return None
|
||||
|
||||
return anthropic_beta_header
|
||||
# Return the mapped value (could be None if unsupported)
|
||||
return provider_mapping[anthropic_beta_header]
|
||||
|
||||
|
||||
def update_headers_with_filtered_beta(
|
||||
|
|
@ -208,7 +221,7 @@ def update_headers_with_filtered_beta(
|
|||
|
||||
def get_unsupported_headers(provider: str) -> List[str]:
|
||||
"""
|
||||
Get all beta headers that are unsupported by a provider.
|
||||
Get all beta headers that are unsupported by a provider (have null values in mapping).
|
||||
|
||||
Args:
|
||||
provider: Provider name
|
||||
|
|
@ -218,4 +231,7 @@ def get_unsupported_headers(provider: str) -> List[str]:
|
|||
"""
|
||||
config = _load_beta_headers_config()
|
||||
provider = get_provider_name(provider)
|
||||
return config.get(provider, [])
|
||||
provider_mapping = config.get(provider, {})
|
||||
|
||||
# Return headers with null values
|
||||
return [header for header, value in provider_mapping.items() if value is None]
|
||||
|
|
|
|||
|
|
@ -237,17 +237,37 @@ def batch_completion_models_all_responses(*args, **kwargs):
|
|||
if "model" in kwargs:
|
||||
kwargs.pop("model")
|
||||
if "models" in kwargs:
|
||||
models = kwargs["models"]
|
||||
kwargs.pop("models")
|
||||
models = kwargs.pop("models")
|
||||
else:
|
||||
raise Exception("'models' param not in kwargs")
|
||||
|
||||
if isinstance(models, str):
|
||||
models = [models]
|
||||
elif isinstance(models, (list, tuple)):
|
||||
models = list(models)
|
||||
else:
|
||||
raise TypeError("'models' must be a string or list of strings")
|
||||
|
||||
if len(models) == 0:
|
||||
return []
|
||||
|
||||
responses = []
|
||||
|
||||
with concurrent.futures.ThreadPoolExecutor(max_workers=len(models)) as executor:
|
||||
for idx, model in enumerate(models):
|
||||
future = executor.submit(litellm.completion, *args, model=model, **kwargs)
|
||||
if future.result() is not None:
|
||||
responses.append(future.result())
|
||||
futures = [
|
||||
executor.submit(litellm.completion, *args, model=model, **kwargs)
|
||||
for model in models
|
||||
]
|
||||
|
||||
for future in futures:
|
||||
try:
|
||||
result = future.result()
|
||||
if result is not None:
|
||||
responses.append(result)
|
||||
except Exception as e:
|
||||
print_verbose(
|
||||
f"batch_completion_models_all_responses: model request failed: {str(e)}"
|
||||
)
|
||||
continue
|
||||
|
||||
return responses
|
||||
|
|
|
|||
|
|
@ -213,6 +213,10 @@ REDIS_DAILY_AGENT_SPEND_UPDATE_BUFFER_KEY = "litellm_daily_agent_spend_update_bu
|
|||
REDIS_DAILY_TAG_SPEND_UPDATE_BUFFER_KEY = "litellm_daily_tag_spend_update_buffer"
|
||||
MAX_REDIS_BUFFER_DEQUEUE_COUNT = int(os.getenv("MAX_REDIS_BUFFER_DEQUEUE_COUNT", 100))
|
||||
MAX_SIZE_IN_MEMORY_QUEUE = int(os.getenv("MAX_SIZE_IN_MEMORY_QUEUE", 2000))
|
||||
# Bounds asyncio.Queue() instances (log queues, spend update queues, etc.) to prevent unbounded memory growth
|
||||
LITELLM_ASYNCIO_QUEUE_MAXSIZE = int(
|
||||
os.getenv("LITELLM_ASYNCIO_QUEUE_MAXSIZE", 1000)
|
||||
)
|
||||
MAX_IN_MEMORY_QUEUE_FLUSH_COUNT = int(
|
||||
os.getenv("MAX_IN_MEMORY_QUEUE_FLUSH_COUNT", 1000)
|
||||
)
|
||||
|
|
@ -1306,6 +1310,9 @@ DEFAULT_SLACK_ALERTING_THRESHOLD = int(
|
|||
os.getenv("DEFAULT_SLACK_ALERTING_THRESHOLD", 300)
|
||||
)
|
||||
MAX_TEAM_LIST_LIMIT = int(os.getenv("MAX_TEAM_LIST_LIMIT", 20))
|
||||
MAX_POLICY_ESTIMATE_IMPACT_ROWS = int(
|
||||
os.getenv("MAX_POLICY_ESTIMATE_IMPACT_ROWS", 1000)
|
||||
)
|
||||
DEFAULT_PROMPT_INJECTION_SIMILARITY_THRESHOLD = float(
|
||||
os.getenv("DEFAULT_PROMPT_INJECTION_SIMILARITY_THRESHOLD", 0.7)
|
||||
)
|
||||
|
|
|
|||
|
|
@ -28,6 +28,41 @@ else:
|
|||
|
||||
|
||||
class ArizeLogger(OpenTelemetry):
|
||||
"""
|
||||
Arize logger that sends traces to an Arize endpoint.
|
||||
|
||||
Creates its own dedicated TracerProvider so it can coexist with the
|
||||
generic ``otel`` callback (or any other OTEL-based integration) without
|
||||
fighting over the global ``opentelemetry.trace`` TracerProvider singleton.
|
||||
"""
|
||||
|
||||
def _init_tracing(self, tracer_provider):
|
||||
"""
|
||||
Override to always create a *private* TracerProvider for Arize.
|
||||
|
||||
See ArizePhoenixLogger._init_tracing for full rationale.
|
||||
"""
|
||||
from opentelemetry.sdk.trace import TracerProvider
|
||||
from opentelemetry.trace import SpanKind
|
||||
|
||||
if tracer_provider is not None:
|
||||
self.tracer = tracer_provider.get_tracer("litellm")
|
||||
self.span_kind = SpanKind
|
||||
return
|
||||
|
||||
provider = TracerProvider(resource=self._get_litellm_resource(self.config))
|
||||
provider.add_span_processor(self._get_span_processor())
|
||||
self.tracer = provider.get_tracer("litellm")
|
||||
self.span_kind = SpanKind
|
||||
|
||||
def _init_otel_logger_on_litellm_proxy(self):
|
||||
"""
|
||||
Override: Arize should NOT overwrite the proxy's
|
||||
``open_telemetry_logger``. That attribute is reserved for the
|
||||
primary ``otel`` callback which handles proxy-level parent spans.
|
||||
"""
|
||||
pass
|
||||
|
||||
def set_attributes(self, span: Span, kwargs, response_obj: Optional[Any]):
|
||||
ArizeLogger.set_arize_attributes(span, kwargs, response_obj)
|
||||
return
|
||||
|
|
|
|||
|
|
@ -5,43 +5,211 @@ from litellm._logging import verbose_logger
|
|||
from litellm.integrations.arize import _utils
|
||||
from litellm.integrations.arize._utils import ArizeOTELAttributes
|
||||
from litellm.types.integrations.arize_phoenix import ArizePhoenixConfig
|
||||
from litellm.integrations.opentelemetry import OpenTelemetry
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from opentelemetry.sdk.trace import TracerProvider
|
||||
from opentelemetry.trace import Span as _Span
|
||||
from opentelemetry.trace import SpanKind
|
||||
|
||||
from litellm.integrations.opentelemetry import OpenTelemetry as _OpenTelemetry
|
||||
from litellm.integrations.opentelemetry import OpenTelemetryConfig as _OpenTelemetryConfig
|
||||
from litellm.types.integrations.arize import Protocol as _Protocol
|
||||
|
||||
Protocol = _Protocol
|
||||
OpenTelemetryConfig = _OpenTelemetryConfig
|
||||
Span = Union[_Span, Any]
|
||||
OpenTelemetry = _OpenTelemetry
|
||||
else:
|
||||
Protocol = Any
|
||||
OpenTelemetryConfig = Any
|
||||
Span = Any
|
||||
TracerProvider = Any
|
||||
SpanKind = Any
|
||||
# Import OpenTelemetry at runtime
|
||||
try:
|
||||
from litellm.integrations.opentelemetry import OpenTelemetry
|
||||
except ImportError:
|
||||
OpenTelemetry = None # type: ignore
|
||||
|
||||
|
||||
ARIZE_HOSTED_PHOENIX_ENDPOINT = "https://otlp.arize.com/v1/traces"
|
||||
|
||||
|
||||
class ArizePhoenixLogger(OpenTelemetry):
|
||||
class ArizePhoenixLogger(OpenTelemetry): # type: ignore
|
||||
"""
|
||||
Arize Phoenix logger that sends traces to a Phoenix endpoint.
|
||||
|
||||
Creates its own dedicated TracerProvider so it can coexist with the
|
||||
generic ``otel`` callback (or any other OTEL-based integration) without
|
||||
fighting over the global ``opentelemetry.trace`` TracerProvider singleton.
|
||||
"""
|
||||
|
||||
def _init_tracing(self, tracer_provider):
|
||||
"""
|
||||
Override to always create a *private* TracerProvider for Arize Phoenix.
|
||||
|
||||
The base ``OpenTelemetry._init_tracing`` falls back to the global
|
||||
TracerProvider when one already exists. That causes whichever
|
||||
integration initialises second to silently reuse the first one's
|
||||
exporter, so spans only reach one destination.
|
||||
|
||||
By creating our own provider we guarantee Arize Phoenix always gets
|
||||
its own exporter pipeline, regardless of initialisation order.
|
||||
"""
|
||||
from opentelemetry.sdk.trace import TracerProvider
|
||||
from opentelemetry.trace import SpanKind
|
||||
|
||||
if tracer_provider is not None:
|
||||
# Explicitly supplied (e.g. in tests) — honour it.
|
||||
self.tracer = tracer_provider.get_tracer("litellm")
|
||||
self.span_kind = SpanKind
|
||||
return
|
||||
|
||||
# Always create a dedicated provider — never touch the global one.
|
||||
provider = TracerProvider(resource=self._get_litellm_resource(self.config))
|
||||
provider.add_span_processor(self._get_span_processor())
|
||||
self.tracer = provider.get_tracer("litellm")
|
||||
self.span_kind = SpanKind
|
||||
verbose_logger.debug(
|
||||
"ArizePhoenixLogger: Created dedicated TracerProvider "
|
||||
"(endpoint=%s, exporter=%s)",
|
||||
self.config.endpoint,
|
||||
self.config.exporter,
|
||||
)
|
||||
|
||||
def _init_otel_logger_on_litellm_proxy(self):
|
||||
"""
|
||||
Override: Arize Phoenix should NOT overwrite the proxy's
|
||||
``open_telemetry_logger``. That attribute is reserved for the
|
||||
primary ``otel`` callback which handles proxy-level parent spans.
|
||||
"""
|
||||
pass
|
||||
|
||||
def set_attributes(self, span: Span, kwargs, response_obj: Optional[Any]):
|
||||
ArizePhoenixLogger.set_arize_phoenix_attributes(span, kwargs, response_obj)
|
||||
return
|
||||
|
||||
@staticmethod
|
||||
def set_arize_phoenix_attributes(span: Span, kwargs, response_obj):
|
||||
from litellm.integrations.opentelemetry_utils.base_otel_llm_obs_attributes import safe_set_attribute
|
||||
|
||||
_utils.set_attributes(span, kwargs, response_obj, ArizeOTELAttributes)
|
||||
|
||||
# Set project name on the span for all traces to go to custom Phoenix projects
|
||||
config = ArizePhoenixLogger.get_arize_phoenix_config()
|
||||
if config.project_name:
|
||||
from litellm.integrations.opentelemetry_utils.base_otel_llm_obs_attributes import safe_set_attribute
|
||||
safe_set_attribute(span, "openinference.project.name", config.project_name)
|
||||
|
||||
|
||||
# Dynamic project name: check metadata first, then fall back to env var config
|
||||
dynamic_project_name = ArizePhoenixLogger._get_dynamic_project_name(kwargs)
|
||||
if dynamic_project_name:
|
||||
safe_set_attribute(span, "openinference.project.name", dynamic_project_name)
|
||||
else:
|
||||
# Fall back to static config from env var
|
||||
config = ArizePhoenixLogger.get_arize_phoenix_config()
|
||||
if config.project_name:
|
||||
safe_set_attribute(span, "openinference.project.name", config.project_name)
|
||||
|
||||
return
|
||||
|
||||
@staticmethod
|
||||
def _get_dynamic_project_name(kwargs) -> Optional[str]:
|
||||
"""
|
||||
Retrieve dynamic Phoenix project name from request metadata.
|
||||
|
||||
Users can set `metadata.phoenix_project_name` in their request to route
|
||||
traces to different Phoenix projects dynamically.
|
||||
"""
|
||||
standard_logging_payload = kwargs.get("standard_logging_object")
|
||||
if isinstance(standard_logging_payload, dict):
|
||||
metadata = standard_logging_payload.get("metadata")
|
||||
if isinstance(metadata, dict):
|
||||
project_name = metadata.get("phoenix_project_name")
|
||||
if project_name:
|
||||
return str(project_name)
|
||||
|
||||
# Also check litellm_params.metadata for SDK usage
|
||||
litellm_params = kwargs.get("litellm_params")
|
||||
if isinstance(litellm_params, dict):
|
||||
metadata = litellm_params.get("metadata") or {}
|
||||
else:
|
||||
metadata = {}
|
||||
if isinstance(metadata, dict):
|
||||
project_name = metadata.get("phoenix_project_name")
|
||||
if project_name:
|
||||
return str(project_name)
|
||||
|
||||
return None
|
||||
|
||||
def _handle_success(self, kwargs, response_obj, start_time, end_time):
|
||||
"""
|
||||
Override to prevent creating duplicate litellm_request spans when a proxy parent span exists.
|
||||
|
||||
ArizePhoenixLogger should reuse the proxy parent span instead of creating a new litellm_request span,
|
||||
to maintain a shallow span hierarchy as expected by Arize Phoenix.
|
||||
"""
|
||||
from opentelemetry.trace import Status, StatusCode
|
||||
from litellm.secret_managers.main import get_secret_bool
|
||||
from litellm.integrations.opentelemetry import LITELLM_PROXY_REQUEST_SPAN_NAME
|
||||
|
||||
verbose_logger.debug(
|
||||
"ArizePhoenixLogger: Logging kwargs: %s, OTEL config settings=%s",
|
||||
kwargs,
|
||||
self.config,
|
||||
)
|
||||
ctx, parent_span = self._get_span_context(kwargs)
|
||||
|
||||
# ArizePhoenixLogger NEVER creates a litellm_request span when a proxy parent span exists
|
||||
# This is different from the base OpenTelemetry behavior which respects USE_OTEL_LITELLM_REQUEST_SPAN
|
||||
should_create_primary_span = parent_span is None or (
|
||||
parent_span.name != LITELLM_PROXY_REQUEST_SPAN_NAME
|
||||
and get_secret_bool("USE_OTEL_LITELLM_REQUEST_SPAN")
|
||||
)
|
||||
|
||||
if should_create_primary_span:
|
||||
# Create a new litellm_request span
|
||||
span = self._start_primary_span(
|
||||
kwargs, response_obj, start_time, end_time, ctx
|
||||
)
|
||||
# Raw-request sub-span (if enabled) - child of litellm_request span
|
||||
self._maybe_log_raw_request(
|
||||
kwargs, response_obj, start_time, end_time, span
|
||||
)
|
||||
# Ensure proxy-request parent span is annotated with the actual operation kind
|
||||
if (
|
||||
parent_span is not None
|
||||
and parent_span.name == LITELLM_PROXY_REQUEST_SPAN_NAME
|
||||
):
|
||||
self.set_attributes(parent_span, kwargs, response_obj)
|
||||
else:
|
||||
# Do not create primary span (keep hierarchy shallow when parent exists)
|
||||
span = None
|
||||
# Only set attributes if the span is still recording (not closed)
|
||||
# Note: parent_span is guaranteed to be not None here
|
||||
if parent_span.is_recording():
|
||||
parent_span.set_status(Status(StatusCode.OK))
|
||||
self.set_attributes(parent_span, kwargs, response_obj)
|
||||
# Raw-request as direct child of parent_span
|
||||
self._maybe_log_raw_request(
|
||||
kwargs, response_obj, start_time, end_time, parent_span
|
||||
)
|
||||
|
||||
# 3. Guardrail span
|
||||
self._create_guardrail_span(kwargs=kwargs, context=ctx)
|
||||
|
||||
# 4. Metrics & cost recording
|
||||
self._record_metrics(kwargs, response_obj, start_time, end_time)
|
||||
|
||||
# 5. Semantic logs.
|
||||
if self.config.enable_events:
|
||||
log_span = span if span is not None else parent_span
|
||||
if log_span is not None:
|
||||
self._emit_semantic_logs(kwargs, response_obj, log_span)
|
||||
|
||||
# 6. Do NOT end parent span - it should be managed by its creator
|
||||
# External spans (from Langfuse, user code, HTTP headers, global context) must not be closed by LiteLLM
|
||||
# However, proxy-created spans should be closed here
|
||||
if (
|
||||
parent_span is not None
|
||||
and parent_span.name == LITELLM_PROXY_REQUEST_SPAN_NAME
|
||||
):
|
||||
parent_span.end(end_time=self._to_ns(end_time))
|
||||
|
||||
@staticmethod
|
||||
def get_arize_phoenix_config() -> ArizePhoenixConfig:
|
||||
"""
|
||||
|
|
|
|||
|
|
@ -103,10 +103,15 @@ class CBFTransformer:
|
|||
# Use team_alias if available, otherwise team_id, otherwise fallback to 'unknown'
|
||||
entity_id = str(team_alias) if team_alias else (str(team_id) if team_id else 'unknown')
|
||||
|
||||
# Get alias fields if they exist
|
||||
api_key_alias = row.get('api_key_alias')
|
||||
organization_alias = row.get('organization_alias')
|
||||
project_alias = row.get('project_alias')
|
||||
user_alias = row.get('user_alias')
|
||||
|
||||
dimensions = {
|
||||
'entity_type': CZEntityType.TEAM.value,
|
||||
'entity_id': entity_id,
|
||||
'team_id': str(team_id) if team_id else 'unknown',
|
||||
'team_alias': str(team_alias) if team_alias else 'unknown',
|
||||
'model': model,
|
||||
'model_group': str(row.get('model_group', '')),
|
||||
|
|
@ -119,28 +124,37 @@ class CBFTransformer:
|
|||
'failed_requests': str(row.get('failed_requests', 0)),
|
||||
'cache_creation_tokens': str(row.get('cache_creation_input_tokens', 0)),
|
||||
'cache_read_tokens': str(row.get('cache_read_input_tokens', 0)),
|
||||
'organization_alias': str(organization_alias) if organization_alias else '',
|
||||
'project_alias': str(project_alias) if project_alias else '',
|
||||
'user_alias': str(user_alias) if user_alias else '',
|
||||
}
|
||||
|
||||
# Extract CZRN components to populate corresponding CBF columns
|
||||
czrn_components = self.czrn_generator.extract_components(resource_id)
|
||||
service_type, provider, region, owner_account_id, resource_type, cloud_local_id = czrn_components
|
||||
|
||||
# Build resource/account as concat of api_key_alias and api_key_prefix
|
||||
resource_account = f"{api_key_alias}|{api_key_hash}" if api_key_alias else api_key_hash
|
||||
|
||||
# CloudZero CBF format with proper column names
|
||||
cbf_record = {
|
||||
# Required CBF fields
|
||||
'time/usage_start': usage_date.isoformat() if usage_date else None, # Required: ISO-formatted UTC datetime
|
||||
'cost/cost': float(row.get('spend', 0.0)), # Required: billed cost
|
||||
'resource/id': resource_id, # Required when resource tags are present
|
||||
'resource/id': model, # Send model name
|
||||
|
||||
# Usage metrics for token consumption
|
||||
'usage/amount': total_tokens, # Numeric value of tokens consumed
|
||||
'usage/units': 'tokens', # Description of token units
|
||||
|
||||
# CBF fields that correspond to CZRN components
|
||||
'resource/service': service_type, # Maps to CZRN service-type (litellm)
|
||||
'resource/account': owner_account_id, # Maps to CZRN owner-account-id (entity_id)
|
||||
# CBF fields - updated per LIT-1907
|
||||
'resource/service': str(row.get('model_group', '')), # Send model_group
|
||||
'resource/account': resource_account, # Send api_key_alias|api_key_prefix
|
||||
'resource/region': region, # Maps to CZRN region (cross-region)
|
||||
'resource/usage_family': resource_type, # Maps to CZRN resource-type (llm-usage)
|
||||
'resource/usage_family': str(row.get('custom_llm_provider', '')), # Send provider
|
||||
|
||||
# Action field
|
||||
'action/operation': str(team_id) if team_id else '', # Send team_id
|
||||
|
||||
# Line item details
|
||||
'lineitem/type': 'Usage', # Standard usage line item
|
||||
|
|
@ -155,13 +169,11 @@ class CBFTransformer:
|
|||
if value and value != 'N/A' and value != 'unknown': # Only add meaningful tags
|
||||
cbf_record[f'resource/tag:{key}'] = str(value)
|
||||
|
||||
# Add token breakdown as resource tags for analysis
|
||||
# Add token breakdown as resource tags for analysis (excluding total_tokens per LIT-1907)
|
||||
if prompt_tokens > 0:
|
||||
cbf_record['resource/tag:prompt_tokens'] = str(prompt_tokens)
|
||||
if completion_tokens > 0:
|
||||
cbf_record['resource/tag:completion_tokens'] = str(completion_tokens)
|
||||
if total_tokens > 0:
|
||||
cbf_record['resource/tag:total_tokens'] = str(total_tokens)
|
||||
|
||||
return CBFRecord(cbf_record)
|
||||
|
||||
|
|
|
|||
|
|
@ -9,6 +9,7 @@ from typing import TYPE_CHECKING, Any, Dict, List, Optional, Tuple
|
|||
from urllib.parse import quote
|
||||
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.constants import LITELLM_ASYNCIO_QUEUE_MAXSIZE
|
||||
from litellm.integrations.additional_logging_utils import AdditionalLoggingUtils
|
||||
from litellm.integrations.gcs_bucket.gcs_bucket_base import GCSBucketBase
|
||||
from litellm.proxy._types import CommonProxyErrors
|
||||
|
|
@ -41,7 +42,9 @@ class GCSBucketLogger(GCSBucketBase, AdditionalLoggingUtils):
|
|||
batch_size=self.batch_size,
|
||||
flush_interval=self.flush_interval,
|
||||
)
|
||||
self.log_queue: asyncio.Queue[GCSLogQueueItem] = asyncio.Queue() # type: ignore[assignment]
|
||||
self.log_queue: asyncio.Queue[GCSLogQueueItem] = asyncio.Queue( # type: ignore[assignment]
|
||||
maxsize=LITELLM_ASYNCIO_QUEUE_MAXSIZE
|
||||
)
|
||||
asyncio.create_task(self.periodic_flush())
|
||||
AdditionalLoggingUtils.__init__(self)
|
||||
|
||||
|
|
@ -69,6 +72,9 @@ class GCSBucketLogger(GCSBucketBase, AdditionalLoggingUtils):
|
|||
)
|
||||
if logging_payload is None:
|
||||
raise ValueError("standard_logging_object not found in kwargs")
|
||||
# When queue is at maxsize, flush immediately to make room (no blocking, no data dropped)
|
||||
if self.log_queue.full():
|
||||
await self.flush_queue()
|
||||
await self.log_queue.put(
|
||||
GCSLogQueueItem(
|
||||
payload=logging_payload, kwargs=kwargs, response_obj=response_obj
|
||||
|
|
@ -91,9 +97,9 @@ class GCSBucketLogger(GCSBucketBase, AdditionalLoggingUtils):
|
|||
)
|
||||
if logging_payload is None:
|
||||
raise ValueError("standard_logging_object not found in kwargs")
|
||||
# Add to logging queue - this will be flushed periodically
|
||||
# Use asyncio.Queue.put() for thread-safe concurrent access
|
||||
# If queue is full, this will block until space is available (backpressure)
|
||||
# When queue is at maxsize, flush immediately to make room (no blocking, no data dropped)
|
||||
if self.log_queue.full():
|
||||
await self.flush_queue()
|
||||
await self.log_queue.put(
|
||||
GCSLogQueueItem(
|
||||
payload=logging_payload, kwargs=kwargs, response_obj=response_obj
|
||||
|
|
|
|||
|
|
@ -3764,7 +3764,7 @@ def _init_custom_logger_compatible_class( # noqa: PLR0915
|
|||
from litellm.integrations.opentelemetry import OpenTelemetry
|
||||
|
||||
for callback in _in_memory_loggers:
|
||||
if isinstance(callback, OpenTelemetry):
|
||||
if type(callback) is OpenTelemetry:
|
||||
return callback # type: ignore
|
||||
otel_logger = OpenTelemetry(
|
||||
**_get_custom_logger_settings_from_proxy_server(
|
||||
|
|
|
|||
|
|
@ -140,9 +140,14 @@ def should_redact_message_logging(model_call_details: dict) -> bool:
|
|||
|
||||
metadata_field = get_metadata_variable_name_from_kwargs(litellm_params)
|
||||
metadata = litellm_params.get(metadata_field, {})
|
||||
|
||||
if not isinstance(metadata, dict):
|
||||
# Fall back: litellm_metadata was None, try metadata
|
||||
metadata = litellm_params.get("metadata", {})
|
||||
if not isinstance(metadata, dict):
|
||||
metadata = {}
|
||||
|
||||
# Get headers from the metadata
|
||||
request_headers = metadata.get("headers", {}) if isinstance(metadata, dict) else {}
|
||||
request_headers = metadata.get("headers", {})
|
||||
|
||||
# Check for headers that explicitly control redaction
|
||||
if request_headers and bool(
|
||||
|
|
|
|||
|
|
@ -58,6 +58,9 @@ from litellm.types.utils import (
|
|||
|
||||
from ...base import BaseLLM
|
||||
from ..common_utils import AnthropicError, process_anthropic_headers
|
||||
from litellm.anthropic_beta_headers_manager import (
|
||||
update_headers_with_filtered_beta,
|
||||
)
|
||||
from .transformation import AnthropicConfig
|
||||
|
||||
if TYPE_CHECKING:
|
||||
|
|
@ -333,6 +336,10 @@ class AnthropicChatCompletion(BaseLLM):
|
|||
litellm_params=litellm_params,
|
||||
)
|
||||
|
||||
headers = update_headers_with_filtered_beta(
|
||||
headers=headers, provider=custom_llm_provider
|
||||
)
|
||||
|
||||
config = ProviderConfigManager.get_provider_chat_config(
|
||||
model=model,
|
||||
provider=LlmProviders(custom_llm_provider),
|
||||
|
|
|
|||
|
|
@ -834,6 +834,10 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
"sonnet-4-5",
|
||||
"opus-4.1",
|
||||
"opus-4-1",
|
||||
"opus-4.5",
|
||||
"opus-4-5",
|
||||
"opus-4.6",
|
||||
"opus-4-6",
|
||||
}
|
||||
):
|
||||
_output_format = (
|
||||
|
|
@ -931,6 +935,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
Translate system message to anthropic format.
|
||||
|
||||
Removes system message from the original list and returns a new list of anthropic system message content.
|
||||
Filters out system messages containing x-anthropic-billing-header metadata.
|
||||
"""
|
||||
system_prompt_indices = []
|
||||
anthropic_system_message_list: List[AnthropicSystemMessageContent] = []
|
||||
|
|
@ -942,6 +947,9 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
# Skip empty text blocks - Anthropic API raises errors for empty text
|
||||
if not system_message_block["content"]:
|
||||
continue
|
||||
# Skip system messages containing x-anthropic-billing-header metadata
|
||||
if system_message_block["content"].startswith("x-anthropic-billing-header:"):
|
||||
continue
|
||||
anthropic_system_message_content = AnthropicSystemMessageContent(
|
||||
type="text",
|
||||
text=system_message_block["content"],
|
||||
|
|
@ -960,6 +968,9 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
text_value = _content.get("text")
|
||||
if _content.get("type") == "text" and not text_value:
|
||||
continue
|
||||
# Skip system messages containing x-anthropic-billing-header metadata
|
||||
if _content.get("type") == "text" and text_value and text_value.startswith("x-anthropic-billing-header:"):
|
||||
continue
|
||||
anthropic_system_message_content = (
|
||||
AnthropicSystemMessageContent(
|
||||
type=_content.get("type"),
|
||||
|
|
|
|||
|
|
@ -2,9 +2,6 @@ from typing import Any, AsyncIterator, Dict, List, Optional, Tuple
|
|||
|
||||
import httpx
|
||||
|
||||
from litellm.anthropic_beta_headers_manager import (
|
||||
update_headers_with_filtered_beta,
|
||||
)
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj
|
||||
from litellm.litellm_core_utils.litellm_logging import verbose_logger
|
||||
from litellm.llms.base_llm.anthropic_messages.transformation import (
|
||||
|
|
@ -52,6 +49,40 @@ class AnthropicMessagesConfig(BaseAnthropicMessagesConfig):
|
|||
# TODO: Add Anthropic `metadata` support
|
||||
# "metadata",
|
||||
]
|
||||
|
||||
@staticmethod
|
||||
def _filter_billing_headers_from_system(system_param):
|
||||
"""
|
||||
Filter out x-anthropic-billing-header metadata from system parameter.
|
||||
|
||||
Args:
|
||||
system_param: Can be a string or a list of system message content blocks
|
||||
|
||||
Returns:
|
||||
Filtered system parameter (string or list), or None if all content was filtered
|
||||
"""
|
||||
if isinstance(system_param, str):
|
||||
# If it's a string and starts with billing header, filter it out
|
||||
if system_param.startswith("x-anthropic-billing-header:"):
|
||||
return None
|
||||
return system_param
|
||||
elif isinstance(system_param, list):
|
||||
# Filter list of system content blocks
|
||||
filtered_list = []
|
||||
for content_block in system_param:
|
||||
if isinstance(content_block, dict):
|
||||
text = content_block.get("text", "")
|
||||
content_type = content_block.get("type", "")
|
||||
# Skip text blocks that start with billing header
|
||||
if content_type == "text" and text.startswith("x-anthropic-billing-header:"):
|
||||
continue
|
||||
filtered_list.append(content_block)
|
||||
else:
|
||||
# Keep non-dict items as-is
|
||||
filtered_list.append(content_block)
|
||||
return filtered_list if len(filtered_list) > 0 else None
|
||||
else:
|
||||
return system_param
|
||||
|
||||
def get_complete_url(
|
||||
self,
|
||||
|
|
@ -96,11 +127,6 @@ class AnthropicMessagesConfig(BaseAnthropicMessagesConfig):
|
|||
optional_params=optional_params,
|
||||
)
|
||||
|
||||
headers = update_headers_with_filtered_beta(
|
||||
headers=headers,
|
||||
provider="anthropic",
|
||||
)
|
||||
|
||||
return headers, api_base
|
||||
|
||||
def transform_anthropic_messages_request(
|
||||
|
|
@ -123,6 +149,17 @@ class AnthropicMessagesConfig(BaseAnthropicMessagesConfig):
|
|||
message="max_tokens is required for Anthropic /v1/messages API",
|
||||
status_code=400,
|
||||
)
|
||||
|
||||
# Filter out x-anthropic-billing-header from system messages
|
||||
system_param = anthropic_messages_optional_request_params.get("system")
|
||||
if system_param is not None:
|
||||
filtered_system = self._filter_billing_headers_from_system(system_param)
|
||||
if filtered_system is not None and len(filtered_system) > 0:
|
||||
anthropic_messages_optional_request_params["system"] = filtered_system
|
||||
else:
|
||||
# Remove system parameter if all content was filtered out
|
||||
anthropic_messages_optional_request_params.pop("system", None)
|
||||
|
||||
####### get required params for all anthropic messages requests ######
|
||||
verbose_logger.debug(f"TRANSFORMATION DEBUG - Messages: {messages}")
|
||||
anthropic_messages_request: AnthropicMessagesRequest = AnthropicMessagesRequest(
|
||||
|
|
|
|||
|
|
@ -105,6 +105,7 @@ class AzureOpenAIConfig(BaseConfig):
|
|||
"modalities",
|
||||
"audio",
|
||||
"web_search_options",
|
||||
"prompt_cache_key",
|
||||
]
|
||||
|
||||
def _is_response_format_supported_model(self, model: str) -> bool:
|
||||
|
|
|
|||
|
|
@ -3,9 +3,6 @@ Azure Anthropic messages transformation config - extends AnthropicMessagesConfig
|
|||
"""
|
||||
from typing import TYPE_CHECKING, Any, List, Optional, Tuple
|
||||
|
||||
from litellm.anthropic_beta_headers_manager import (
|
||||
update_headers_with_filtered_beta,
|
||||
)
|
||||
from litellm.llms.anthropic.experimental_pass_through.messages.transformation import (
|
||||
AnthropicMessagesConfig,
|
||||
)
|
||||
|
|
@ -65,18 +62,11 @@ class AzureAnthropicMessagesConfig(AnthropicMessagesConfig):
|
|||
if "content-type" not in headers:
|
||||
headers["content-type"] = "application/json"
|
||||
|
||||
# Update headers with anthropic beta features (context management, tool search, etc.)
|
||||
headers = self._update_headers_with_anthropic_beta(
|
||||
headers=headers,
|
||||
optional_params=optional_params,
|
||||
)
|
||||
|
||||
# Filter out unsupported beta headers for Azure AI
|
||||
headers = update_headers_with_filtered_beta(
|
||||
headers=headers,
|
||||
provider="azure_ai",
|
||||
)
|
||||
|
||||
return headers, api_base
|
||||
|
||||
def get_complete_url(
|
||||
|
|
|
|||
|
|
@ -2,10 +2,6 @@
|
|||
Azure Anthropic transformation config - extends AnthropicConfig with Azure authentication
|
||||
"""
|
||||
from typing import TYPE_CHECKING, Dict, List, Optional, Union
|
||||
|
||||
from litellm.anthropic_beta_headers_manager import (
|
||||
update_headers_with_filtered_beta,
|
||||
)
|
||||
from litellm.llms.anthropic.chat.transformation import AnthropicConfig
|
||||
from litellm.llms.azure.common_utils import BaseAzureLLM
|
||||
from litellm.types.llms.openai import AllMessageValues
|
||||
|
|
@ -90,11 +86,6 @@ class AzureAnthropicConfig(AnthropicConfig):
|
|||
if "anthropic-version" not in headers:
|
||||
headers["anthropic-version"] = "2023-06-01"
|
||||
|
||||
# Filter out unsupported beta headers for Azure AI
|
||||
headers = update_headers_with_filtered_beta(
|
||||
headers=headers,
|
||||
provider="azure_ai",
|
||||
)
|
||||
|
||||
return headers
|
||||
|
||||
|
|
|
|||
|
|
@ -11,12 +11,14 @@ from litellm.litellm_core_utils.prompt_templates.common_utils import (
|
|||
_audio_or_image_in_message_content,
|
||||
convert_content_list_to_str,
|
||||
)
|
||||
from litellm.llms.azure.common_utils import BaseAzureLLM
|
||||
from litellm.llms.base_llm.chat.transformation import LiteLLMLoggingObj
|
||||
from litellm.llms.openai.common_utils import drop_params_from_unprocessable_entity_error
|
||||
from litellm.llms.openai.openai import OpenAIConfig
|
||||
from litellm.llms.xai.chat.transformation import XAIChatConfig
|
||||
from litellm.secret_managers.main import get_secret_str
|
||||
from litellm.types.llms.openai import AllMessageValues
|
||||
from litellm.types.router import GenericLiteLLMParams
|
||||
from litellm.types.utils import ModelResponse, ProviderField
|
||||
from litellm.utils import _add_path_to_api_base, supports_tool_choice
|
||||
|
||||
|
|
@ -64,12 +66,21 @@ class AzureAIStudioConfig(OpenAIConfig):
|
|||
api_key: Optional[str] = None,
|
||||
api_base: Optional[str] = None,
|
||||
) -> dict:
|
||||
if api_base and self._should_use_api_key_header(api_base):
|
||||
headers["api-key"] = api_key
|
||||
if api_key:
|
||||
if api_base and self._should_use_api_key_header(api_base):
|
||||
headers["api-key"] = api_key
|
||||
else:
|
||||
headers["Authorization"] = f"Bearer {api_key}"
|
||||
else:
|
||||
headers["Authorization"] = f"Bearer {api_key}"
|
||||
# No api_key provided — fall back to Azure AD token-based auth
|
||||
litellm_params_obj = GenericLiteLLMParams(
|
||||
**(litellm_params if isinstance(litellm_params, dict) else {})
|
||||
)
|
||||
headers = BaseAzureLLM._base_validate_azure_environment(
|
||||
headers=headers, litellm_params=litellm_params_obj
|
||||
)
|
||||
|
||||
headers["Content-Type"] = "application/json" # tell Azure AI Studio to expect JSON
|
||||
headers["Content-Type"] = "application/json"
|
||||
|
||||
return headers
|
||||
|
||||
|
|
|
|||
|
|
@ -211,25 +211,13 @@ class BaseAWSLLM:
|
|||
aws_external_id=aws_external_id,
|
||||
)
|
||||
elif aws_role_name is not None:
|
||||
# Check if we're in IRSA and trying to assume the same role we already have
|
||||
current_role_arn = os.getenv("AWS_ROLE_ARN")
|
||||
web_identity_token_file = os.getenv("AWS_WEB_IDENTITY_TOKEN_FILE")
|
||||
|
||||
# In IRSA environments, we should skip role assumption if we're already running as the target role
|
||||
# This is true when:
|
||||
# 1. We have AWS_ROLE_ARN set (current role)
|
||||
# 2. We have AWS_WEB_IDENTITY_TOKEN_FILE set (IRSA environment)
|
||||
# 3. The current role matches the requested role
|
||||
if (
|
||||
current_role_arn
|
||||
and web_identity_token_file
|
||||
and current_role_arn == aws_role_name
|
||||
):
|
||||
# Check if we're already running as the target role and can skip assumption
|
||||
# This handles IRSA (EKS), ECS task roles, and EC2 instance profiles
|
||||
if self._is_already_running_as_role(aws_role_name, ssl_verify=ssl_verify):
|
||||
verbose_logger.debug(
|
||||
"Using IRSA same-role optimization: calling _auth_with_env_vars"
|
||||
"Already running as target role %s, using ambient credentials",
|
||||
aws_role_name,
|
||||
)
|
||||
# We're already running as this role via IRSA, no need to assume it again
|
||||
# Use the default boto3 credentials (which will use the IRSA credentials)
|
||||
credentials, _cache_ttl = self._auth_with_env_vars()
|
||||
else:
|
||||
verbose_logger.debug(
|
||||
|
|
@ -553,6 +541,107 @@ class BaseAWSLLM:
|
|||
aws_region_name = "us-west-2"
|
||||
return aws_region_name
|
||||
|
||||
@staticmethod
|
||||
def _parse_arn_account_and_role_name(
|
||||
arn: str,
|
||||
) -> Optional[Tuple[str, str, str]]:
|
||||
"""
|
||||
Parse an ARN and return (partition, account_id, role_name).
|
||||
|
||||
Handles:
|
||||
- arn:aws:iam::123456789012:role/MyRole
|
||||
- arn:aws:iam::123456789012:role/path/to/MyRole
|
||||
- arn:aws:sts::123456789012:assumed-role/MyRole/session-name
|
||||
|
||||
Returns None if the ARN cannot be parsed.
|
||||
"""
|
||||
# ARN format: arn:PARTITION:SERVICE:REGION:ACCOUNT:RESOURCE
|
||||
parts = arn.split(":")
|
||||
if len(parts) < 6 or parts[0] != "arn":
|
||||
return None
|
||||
|
||||
partition = parts[1] # e.g. "aws", "aws-cn", "aws-us-gov"
|
||||
account_id = parts[4]
|
||||
resource = ":".join(parts[5:]) # rejoin in case resource contains colons
|
||||
|
||||
if resource.startswith("role/"):
|
||||
# arn:aws:iam::ACCOUNT:role/[path/]ROLE_NAME
|
||||
role_name = resource.split("/")[-1]
|
||||
elif resource.startswith("assumed-role/"):
|
||||
# arn:aws:sts::ACCOUNT:assumed-role/ROLE_NAME/SESSION
|
||||
role_parts = resource.split("/")
|
||||
if len(role_parts) >= 2:
|
||||
role_name = role_parts[1]
|
||||
else:
|
||||
return None
|
||||
else:
|
||||
return None
|
||||
|
||||
return partition, account_id, role_name
|
||||
|
||||
def _is_already_running_as_role(
|
||||
self,
|
||||
aws_role_name: str,
|
||||
ssl_verify: Optional[Union[bool, str]] = None,
|
||||
) -> bool:
|
||||
"""
|
||||
Check if the current environment is already running as the target IAM role.
|
||||
|
||||
This handles multiple AWS environments:
|
||||
- IRSA (EKS): AWS_ROLE_ARN + AWS_WEB_IDENTITY_TOKEN_FILE are set
|
||||
- ECS task roles: Uses sts:GetCallerIdentity to check current role ARN
|
||||
- EC2 instance profiles: Uses sts:GetCallerIdentity to check current role ARN
|
||||
|
||||
Compares partition, account ID, and role name to avoid cross-account
|
||||
false matches.
|
||||
|
||||
Returns True if the current identity matches the target role, meaning
|
||||
we can skip sts:AssumeRole and use ambient credentials directly.
|
||||
"""
|
||||
target_parsed = self._parse_arn_account_and_role_name(aws_role_name)
|
||||
if target_parsed is None:
|
||||
return False
|
||||
|
||||
target_partition, target_account, target_role = target_parsed
|
||||
|
||||
# Fast path: IRSA environment check (no API call needed)
|
||||
current_role_arn = os.getenv("AWS_ROLE_ARN")
|
||||
web_identity_token_file = os.getenv("AWS_WEB_IDENTITY_TOKEN_FILE")
|
||||
if current_role_arn and web_identity_token_file:
|
||||
return current_role_arn == aws_role_name
|
||||
|
||||
# For ECS/EC2: call sts:GetCallerIdentity to check if already running as the role
|
||||
try:
|
||||
import boto3
|
||||
|
||||
with tracer.trace("boto3.client(sts).get_caller_identity"):
|
||||
sts_client = boto3.client(
|
||||
"sts", verify=self._get_ssl_verify(ssl_verify)
|
||||
)
|
||||
identity = sts_client.get_caller_identity()
|
||||
caller_arn = identity.get("Arn", "")
|
||||
|
||||
caller_parsed = self._parse_arn_account_and_role_name(caller_arn)
|
||||
if caller_parsed is not None:
|
||||
caller_partition, caller_account, caller_role = caller_parsed
|
||||
if (
|
||||
caller_partition == target_partition
|
||||
and caller_account == target_account
|
||||
and caller_role == target_role
|
||||
):
|
||||
verbose_logger.debug(
|
||||
"Current identity already matches target role: %s",
|
||||
aws_role_name,
|
||||
)
|
||||
return True
|
||||
|
||||
except Exception as e:
|
||||
verbose_logger.debug(
|
||||
"Could not determine current role identity: %s", str(e)
|
||||
)
|
||||
|
||||
return False
|
||||
|
||||
@tracer.wrap()
|
||||
def _auth_with_web_identity_token(
|
||||
self,
|
||||
|
|
@ -867,7 +956,35 @@ class BaseAWSLLM:
|
|||
if aws_external_id is not None:
|
||||
assume_role_params["ExternalId"] = aws_external_id
|
||||
|
||||
sts_response = sts_client.assume_role(**assume_role_params)
|
||||
try:
|
||||
sts_response = sts_client.assume_role(**assume_role_params)
|
||||
except Exception as e:
|
||||
error_str = str(e)
|
||||
if "AccessDenied" in error_str:
|
||||
# Only fall back to ambient credentials if we can positively
|
||||
# confirm the caller is already the target role (same account,
|
||||
# partition, and role name). This avoids silently using the
|
||||
# wrong identity when there is a genuine trust-policy or
|
||||
# permission misconfiguration.
|
||||
if self._is_already_running_as_role(
|
||||
aws_role_name, ssl_verify=ssl_verify
|
||||
):
|
||||
verbose_logger.warning(
|
||||
"AssumeRole failed for %s (%s). "
|
||||
"Caller is already running as this role; "
|
||||
"falling back to ambient credentials.",
|
||||
aws_role_name,
|
||||
error_str,
|
||||
)
|
||||
return self._auth_with_env_vars()
|
||||
# Genuine permission error — re-raise
|
||||
verbose_logger.error(
|
||||
"AssumeRole AccessDenied for %s and caller is NOT "
|
||||
"the same role. Re-raising. Error: %s",
|
||||
aws_role_name,
|
||||
error_str,
|
||||
)
|
||||
raise
|
||||
|
||||
# Extract the credentials from the response and convert to Session Credentials
|
||||
sts_credentials = sts_response["Credentials"]
|
||||
|
|
|
|||
|
|
@ -13,7 +13,9 @@ from litellm.llms.custom_httpx.http_handler import (
|
|||
)
|
||||
from litellm.types.utils import ModelResponse
|
||||
from litellm.utils import CustomStreamWrapper
|
||||
|
||||
from litellm.anthropic_beta_headers_manager import (
|
||||
update_headers_with_filtered_beta,
|
||||
)
|
||||
from ..base_aws_llm import BaseAWSLLM, Credentials
|
||||
from ..common_utils import BedrockError
|
||||
from .invoke_handler import AWSEventStreamDecoder, MockResponseIterator, make_call
|
||||
|
|
@ -337,7 +339,11 @@ class BedrockConverseLLM(BaseAWSLLM):
|
|||
headers = {"Content-Type": "application/json"}
|
||||
if extra_headers is not None:
|
||||
headers = {"Content-Type": "application/json", **extra_headers}
|
||||
|
||||
|
||||
# Filter beta headers in HTTP headers before making the request
|
||||
headers = update_headers_with_filtered_beta(
|
||||
headers=headers, provider="bedrock_converse"
|
||||
)
|
||||
### ROUTING (ASYNC, STREAMING, SYNC)
|
||||
if acompletion:
|
||||
if isinstance(client, HTTPHandler):
|
||||
|
|
|
|||
|
|
@ -11,9 +11,6 @@ import httpx
|
|||
|
||||
import litellm
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.anthropic_beta_headers_manager import (
|
||||
filter_and_transform_beta_headers,
|
||||
)
|
||||
from litellm.constants import RESPONSE_FORMAT_TOOL_NAME
|
||||
from litellm.litellm_core_utils.core_helpers import (
|
||||
filter_exceptions_from_params,
|
||||
|
|
@ -1132,24 +1129,9 @@ class AmazonConverseConfig(BaseConfig):
|
|||
|
||||
# Set anthropic_beta in additional_request_params if we have any beta features
|
||||
# ONLY apply to Anthropic/Claude models - other models (e.g., Qwen, Llama) don't support this field
|
||||
# and will error with "unknown variant anthropic_beta" if included
|
||||
base_model = BedrockModelInfo.get_base_model(model)
|
||||
if anthropic_beta_list and base_model.startswith("anthropic"):
|
||||
# Remove duplicates while preserving order
|
||||
unique_betas = []
|
||||
seen = set()
|
||||
for beta in anthropic_beta_list:
|
||||
if beta not in seen:
|
||||
unique_betas.append(beta)
|
||||
seen.add(beta)
|
||||
|
||||
filtered_betas = filter_and_transform_beta_headers(
|
||||
beta_headers=unique_betas,
|
||||
provider="bedrock_converse",
|
||||
)
|
||||
|
||||
if filtered_betas:
|
||||
additional_request_params["anthropic_beta"] = filtered_betas
|
||||
additional_request_params["anthropic_beta"] = anthropic_beta_list
|
||||
|
||||
return bedrock_tools, anthropic_beta_list
|
||||
|
||||
|
|
|
|||
|
|
@ -2,7 +2,6 @@ from typing import TYPE_CHECKING, Any, List, Optional
|
|||
|
||||
import httpx
|
||||
|
||||
from litellm.anthropic_beta_headers_manager import filter_and_transform_beta_headers
|
||||
from litellm.llms.anthropic.chat.transformation import AnthropicConfig
|
||||
from litellm.llms.bedrock.chat.invoke_transformations.base_invoke_transformation import (
|
||||
AmazonInvokeConfig,
|
||||
|
|
@ -136,13 +135,7 @@ class AmazonAnthropicClaudeConfig(AmazonInvokeConfig, AnthropicConfig):
|
|||
# Filter out beta headers that Bedrock Invoke doesn't support
|
||||
# Uses centralized configuration from anthropic_beta_headers_config.json
|
||||
beta_list = list(beta_set)
|
||||
filtered_beta_list = filter_and_transform_beta_headers(
|
||||
beta_headers=beta_list,
|
||||
provider="bedrock",
|
||||
)
|
||||
|
||||
if filtered_beta_list:
|
||||
_anthropic_request["anthropic_beta"] = filtered_beta_list
|
||||
_anthropic_request["anthropic_beta"] = beta_list
|
||||
|
||||
return _anthropic_request
|
||||
|
||||
|
|
|
|||
|
|
@ -12,9 +12,6 @@ from typing import (
|
|||
|
||||
import httpx
|
||||
|
||||
from litellm.anthropic_beta_headers_manager import (
|
||||
filter_and_transform_beta_headers,
|
||||
)
|
||||
from litellm.llms.anthropic.common_utils import AnthropicModelInfo
|
||||
from litellm.llms.anthropic.experimental_pass_through.messages.transformation import (
|
||||
AnthropicMessagesConfig,
|
||||
|
|
@ -253,71 +250,6 @@ class AmazonAnthropicClaudeMessagesConfig(
|
|||
|
||||
return any(pattern in model_lower for pattern in supported_patterns)
|
||||
|
||||
def _filter_unsupported_beta_headers_for_bedrock(
|
||||
self, model: str, beta_set: set
|
||||
) -> None:
|
||||
"""
|
||||
Remove beta headers that are not supported on Bedrock for the given model.
|
||||
|
||||
Extended thinking beta headers are only supported on specific Claude 4+ models.
|
||||
Advanced tool use headers are not supported on Bedrock Invoke API, but need to be
|
||||
translated to Bedrock-specific headers for models that support tool search
|
||||
(Claude Opus 4.5, Sonnet 4.5).
|
||||
This prevents 400 "invalid beta flag" errors on Bedrock.
|
||||
|
||||
Note: Bedrock Invoke API fails with a 400 error when unsupported beta headers
|
||||
are sent, returning: {"message":"invalid beta flag"}
|
||||
|
||||
Translation for models supporting tool search (Opus 4.5, Sonnet 4.5):
|
||||
- advanced-tool-use-2025-11-20 -> tool-search-tool-2025-10-19 + tool-examples-2025-10-29
|
||||
|
||||
Args:
|
||||
model: The model name
|
||||
beta_set: The set of beta headers to filter in-place
|
||||
"""
|
||||
# 1. Handle header transformations BEFORE filtering
|
||||
# (advanced-tool-use -> tool-search-tool)
|
||||
# This must happen before filtering because advanced-tool-use is in the unsupported list
|
||||
has_advanced_tool_use = "advanced-tool-use-2025-11-20" in beta_set
|
||||
if has_advanced_tool_use and self._supports_tool_search_on_bedrock(model):
|
||||
beta_set.discard("advanced-tool-use-2025-11-20")
|
||||
beta_set.add("tool-search-tool-2025-10-19")
|
||||
beta_set.add("tool-examples-2025-10-29")
|
||||
|
||||
# 2. Apply provider-level filtering using centralized JSON config
|
||||
beta_list = list(beta_set)
|
||||
filtered_list = filter_and_transform_beta_headers(
|
||||
beta_headers=beta_list,
|
||||
provider="bedrock",
|
||||
)
|
||||
|
||||
# Update the set with filtered headers
|
||||
beta_set.clear()
|
||||
beta_set.update(filtered_list)
|
||||
|
||||
# 2.1. Handle model-specific exceptions: structured-outputs is only supported on Opus 4.6
|
||||
# Re-add structured-outputs if it was in the original set and model is Opus 4.6
|
||||
model_lower = model.lower()
|
||||
is_opus_4_6 = any(pattern in model_lower for pattern in ["opus-4.6", "opus_4.6", "opus-4-6", "opus_4_6"])
|
||||
if is_opus_4_6 and "structured-outputs-2025-11-13" in beta_list:
|
||||
beta_set.add("structured-outputs-2025-11-13")
|
||||
|
||||
# 3. Filter out extended thinking headers for models that don't support them
|
||||
extended_thinking_patterns = [
|
||||
"extended-thinking",
|
||||
"interleaved-thinking",
|
||||
]
|
||||
if not self._supports_extended_thinking_on_bedrock(model):
|
||||
beta_headers_to_remove = set()
|
||||
for beta in beta_set:
|
||||
for pattern in extended_thinking_patterns:
|
||||
if pattern in beta.lower():
|
||||
beta_headers_to_remove.add(beta)
|
||||
break
|
||||
|
||||
for beta in beta_headers_to_remove:
|
||||
beta_set.discard(beta)
|
||||
|
||||
def _get_tool_search_beta_header_for_bedrock(
|
||||
self,
|
||||
model: str,
|
||||
|
|
@ -483,12 +415,11 @@ class AmazonAnthropicClaudeMessagesConfig(
|
|||
beta_set=beta_set,
|
||||
)
|
||||
|
||||
# Filter out unsupported beta headers for Bedrock (e.g., advanced-tool-use, extended-thinking on non-Opus/Sonnet 4 models)
|
||||
self._filter_unsupported_beta_headers_for_bedrock(
|
||||
model=model,
|
||||
beta_set=beta_set,
|
||||
)
|
||||
|
||||
# --- Custom logic: if tool-search-tool-2025-10-19 is present, add tool-examples-2025-10-29 ---
|
||||
if "tool-search-tool-2025-10-19" in beta_set:
|
||||
beta_set.add("tool-examples-2025-10-29")
|
||||
# ------------------------------------------------------------------------------
|
||||
|
||||
if beta_set:
|
||||
anthropic_messages_request["anthropic_beta"] = list(beta_set)
|
||||
|
||||
|
|
|
|||
|
|
@ -81,6 +81,9 @@ from litellm.types.llms.anthropic_skills import (
|
|||
ListSkillsResponse,
|
||||
Skill,
|
||||
)
|
||||
from litellm.anthropic_beta_headers_manager import (
|
||||
update_headers_with_filtered_beta,
|
||||
)
|
||||
from litellm.types.llms.openai import (
|
||||
CreateBatchRequest,
|
||||
CreateFileRequest,
|
||||
|
|
@ -1858,6 +1861,10 @@ class BaseLLMHTTPHandler:
|
|||
api_key=api_key,
|
||||
api_base=api_base,
|
||||
)
|
||||
|
||||
headers = update_headers_with_filtered_beta(
|
||||
headers=headers, provider=custom_llm_provider
|
||||
)
|
||||
|
||||
logging_obj.update_environment_variables(
|
||||
model=model,
|
||||
|
|
|
|||
|
|
@ -838,6 +838,15 @@ class OCIChatConfig(BaseConfig):
|
|||
if not user_messages:
|
||||
raise Exception("No user message found for Cohere model")
|
||||
|
||||
# Extract system messages into preambleOverride
|
||||
system_messages = [msg for msg in messages if msg.get("role") == "system"]
|
||||
preamble_override = None
|
||||
if system_messages:
|
||||
preamble = "\n".join(
|
||||
self._extract_text_content(msg["content"]) for msg in system_messages
|
||||
)
|
||||
if preamble:
|
||||
preamble_override = preamble
|
||||
|
||||
# Create Cohere-specific chat request
|
||||
optional_cohere_params = self._get_optional_params(OCIVendors.COHERE, optional_params)
|
||||
|
|
@ -845,6 +854,7 @@ class OCIChatConfig(BaseConfig):
|
|||
apiFormat="COHERE",
|
||||
message=self._extract_text_content(user_messages[-1]["content"]),
|
||||
chatHistory=self.adapt_messages_to_cohere_standard(messages),
|
||||
preambleOverride=preamble_override,
|
||||
**optional_cohere_params
|
||||
)
|
||||
|
||||
|
|
|
|||
|
|
@ -20,12 +20,12 @@ from typing import (
|
|||
import httpx
|
||||
|
||||
import litellm
|
||||
from litellm.litellm_core_utils.core_helpers import map_finish_reason
|
||||
from litellm.litellm_core_utils.llm_response_utils.convert_dict_to_response import (
|
||||
_extract_reasoning_content,
|
||||
_handle_invalid_parallel_tool_calls,
|
||||
_should_convert_tool_call_to_json_mode,
|
||||
)
|
||||
from litellm.litellm_core_utils.core_helpers import map_finish_reason
|
||||
from litellm.litellm_core_utils.prompt_templates.common_utils import get_tool_call_names
|
||||
from litellm.litellm_core_utils.prompt_templates.image_handling import (
|
||||
async_convert_url_to_base64,
|
||||
|
|
@ -161,6 +161,7 @@ class OpenAIGPTConfig(BaseLLMModelInfo, BaseConfig):
|
|||
"web_search_options",
|
||||
"service_tier",
|
||||
"safety_identifier",
|
||||
"prompt_cache_key",
|
||||
] # works across all models
|
||||
|
||||
model_specific_params = []
|
||||
|
|
|
|||
|
|
@ -1,8 +1,5 @@
|
|||
from typing import Any, Dict, List, Optional, Tuple
|
||||
|
||||
from litellm.anthropic_beta_headers_manager import (
|
||||
update_headers_with_filtered_beta,
|
||||
)
|
||||
from litellm.llms.anthropic.common_utils import AnthropicModelInfo
|
||||
from litellm.llms.anthropic.experimental_pass_through.messages.transformation import (
|
||||
AnthropicMessagesConfig,
|
||||
|
|
@ -105,12 +102,6 @@ class VertexAIPartnerModelsAnthropicMessagesConfig(AnthropicMessagesConfig, Vert
|
|||
if beta_values:
|
||||
headers["anthropic-beta"] = ",".join(beta_values)
|
||||
|
||||
# Filter out unsupported beta headers for Vertex AI
|
||||
headers = update_headers_with_filtered_beta(
|
||||
headers=headers,
|
||||
provider="vertex_ai",
|
||||
)
|
||||
|
||||
return headers, api_base
|
||||
|
||||
def get_complete_url(
|
||||
|
|
|
|||
|
|
@ -6115,6 +6115,17 @@
|
|||
"supports_function_calling": true,
|
||||
"supports_reasoning": true
|
||||
},
|
||||
"bedrock/moonshotai.kimi-k2-thinking": {
|
||||
"input_cost_per_token": 7.3e-07,
|
||||
"litellm_provider": "bedrock",
|
||||
"max_input_tokens": 262144,
|
||||
"max_output_tokens": 262144,
|
||||
"max_tokens": 262144,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 3.03e-06,
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true
|
||||
},
|
||||
"bedrock/moonshotai.kimi-k2.5": {
|
||||
"input_cost_per_token": 7.3e-07,
|
||||
"litellm_provider": "bedrock",
|
||||
|
|
@ -9035,6 +9046,43 @@
|
|||
}
|
||||
]
|
||||
},
|
||||
"dashscope/qwen3-max": {
|
||||
"litellm_provider": "dashscope",
|
||||
"max_input_tokens": 258048,
|
||||
"max_output_tokens": 65536,
|
||||
"max_tokens": 65536,
|
||||
"mode": "chat",
|
||||
"source": "https://www.alibabacloud.com/help/en/model-studio/models",
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true,
|
||||
"tiered_pricing": [
|
||||
{
|
||||
"input_cost_per_token": 1.2e-06,
|
||||
"output_cost_per_token": 6e-06,
|
||||
"range": [
|
||||
0,
|
||||
32000.0
|
||||
]
|
||||
},
|
||||
{
|
||||
"input_cost_per_token": 2.4e-06,
|
||||
"output_cost_per_token": 1.2e-05,
|
||||
"range": [
|
||||
32000.0,
|
||||
128000.0
|
||||
]
|
||||
},
|
||||
{
|
||||
"input_cost_per_token": 3e-06,
|
||||
"output_cost_per_token": 1.5e-05,
|
||||
"range": [
|
||||
128000.0,
|
||||
252000.0
|
||||
]
|
||||
}
|
||||
]
|
||||
},
|
||||
"dashscope/qwq-plus": {
|
||||
"input_cost_per_token": 8e-07,
|
||||
"litellm_provider": "dashscope",
|
||||
|
|
@ -10708,14 +10756,22 @@
|
|||
"input_cost_per_token": 2.8e-07,
|
||||
"input_cost_per_token_cache_hit": 2.8e-08,
|
||||
"litellm_provider": "deepseek",
|
||||
"max_input_tokens": 128000,
|
||||
"max_input_tokens": 131072,
|
||||
"max_output_tokens": 8192,
|
||||
"max_tokens": 8192,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 4.2e-07,
|
||||
"source": "https://api-docs.deepseek.com/quick_start/pricing",
|
||||
"supported_endpoints": [
|
||||
"/v1/chat/completions"
|
||||
],
|
||||
"supports_assistant_prefill": true,
|
||||
"supports_function_calling": true,
|
||||
"supports_native_streaming": true,
|
||||
"supports_parallel_function_calling": true,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_response_schema": true,
|
||||
"supports_system_messages": true,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
"deepseek/deepseek-coder": {
|
||||
|
|
@ -10752,16 +10808,24 @@
|
|||
"input_cost_per_token": 2.8e-07,
|
||||
"input_cost_per_token_cache_hit": 2.8e-08,
|
||||
"litellm_provider": "deepseek",
|
||||
"max_input_tokens": 128000,
|
||||
"max_output_tokens": 8192,
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 131072,
|
||||
"max_output_tokens": 65536,
|
||||
"max_tokens": 65536,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 4.2e-07,
|
||||
"source": "https://api-docs.deepseek.com/quick_start/pricing",
|
||||
"supported_endpoints": [
|
||||
"/v1/chat/completions"
|
||||
],
|
||||
"supports_assistant_prefill": true,
|
||||
"supports_function_calling": true,
|
||||
"supports_function_calling": false,
|
||||
"supports_native_streaming": true,
|
||||
"supports_parallel_function_calling": false,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true
|
||||
"supports_response_schema": true,
|
||||
"supports_system_messages": true,
|
||||
"supports_tool_choice": false
|
||||
},
|
||||
"deepseek/deepseek-v3": {
|
||||
"cache_creation_input_token_cost": 0.0,
|
||||
|
|
|
|||
|
|
@ -6,7 +6,12 @@ from starlette.requests import Request
|
|||
from starlette.types import Scope
|
||||
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.proxy._types import LiteLLM_TeamTable, ProxyException, SpecialHeaders, UserAPIKeyAuth
|
||||
from litellm.proxy._types import (
|
||||
LiteLLM_TeamTable,
|
||||
ProxyException,
|
||||
SpecialHeaders,
|
||||
UserAPIKeyAuth,
|
||||
)
|
||||
from litellm.proxy.auth.user_api_key_auth import user_api_key_auth
|
||||
|
||||
|
||||
|
|
@ -372,45 +377,31 @@ class MCPRequestHandler:
|
|||
return []
|
||||
|
||||
@staticmethod
|
||||
async def _get_key_object_permission(
|
||||
def _get_key_object_permission(
|
||||
user_api_key_auth: Optional[UserAPIKeyAuth] = None,
|
||||
):
|
||||
"""Helper to get key object_permission from cache or DB."""
|
||||
from litellm.proxy.auth.auth_checks import get_object_permission
|
||||
from litellm.proxy.proxy_server import (
|
||||
prisma_client,
|
||||
proxy_logging_obj,
|
||||
user_api_key_cache,
|
||||
)
|
||||
"""
|
||||
Get key object_permission - already loaded by get_key_object() in main auth flow.
|
||||
|
||||
Note: object_permission is automatically populated when the key is fetched via
|
||||
get_key_object() in litellm/proxy/auth/auth_checks.py
|
||||
"""
|
||||
if not user_api_key_auth:
|
||||
return None
|
||||
|
||||
# Already loaded
|
||||
if user_api_key_auth.object_permission:
|
||||
return user_api_key_auth.object_permission
|
||||
|
||||
# Need to fetch from DB
|
||||
if user_api_key_auth.object_permission_id and prisma_client:
|
||||
return await get_object_permission(
|
||||
object_permission_id=user_api_key_auth.object_permission_id,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
parent_otel_span=user_api_key_auth.parent_otel_span,
|
||||
proxy_logging_obj=proxy_logging_obj,
|
||||
)
|
||||
|
||||
return None
|
||||
return user_api_key_auth.object_permission
|
||||
|
||||
@staticmethod
|
||||
async def _get_team_object_permission(
|
||||
user_api_key_auth: Optional[UserAPIKeyAuth] = None,
|
||||
):
|
||||
"""Helper to get team object_permission from cache or DB."""
|
||||
from litellm.proxy.auth.auth_checks import (
|
||||
get_object_permission,
|
||||
get_team_object,
|
||||
)
|
||||
"""
|
||||
Get team object_permission - automatically loaded by get_team_object() in main auth flow.
|
||||
|
||||
Note: object_permission is automatically populated when the team is fetched via
|
||||
get_team_object() in litellm/proxy/auth/auth_checks.py
|
||||
"""
|
||||
from litellm.proxy.auth.auth_checks import get_team_object
|
||||
from litellm.proxy.proxy_server import (
|
||||
prisma_client,
|
||||
proxy_logging_obj,
|
||||
|
|
@ -423,7 +414,7 @@ class MCPRequestHandler:
|
|||
if not user_api_key_auth or not user_api_key_auth.team_id or not prisma_client:
|
||||
return None
|
||||
|
||||
# First get the team object (which may have object_permission already loaded)
|
||||
# Get the team object (which has object_permission already loaded)
|
||||
team_obj: Optional[LiteLLM_TeamTable] = await get_team_object(
|
||||
team_id=user_api_key_auth.team_id,
|
||||
prisma_client=prisma_client,
|
||||
|
|
@ -435,21 +426,7 @@ class MCPRequestHandler:
|
|||
if not team_obj:
|
||||
return None
|
||||
|
||||
# Already loaded
|
||||
if team_obj.object_permission:
|
||||
return team_obj.object_permission
|
||||
|
||||
# Need to fetch from DB using object_permission_id
|
||||
if team_obj.object_permission_id:
|
||||
return await get_object_permission(
|
||||
object_permission_id=team_obj.object_permission_id,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
parent_otel_span=user_api_key_auth.parent_otel_span,
|
||||
proxy_logging_obj=proxy_logging_obj,
|
||||
)
|
||||
|
||||
return None
|
||||
return team_obj.object_permission
|
||||
|
||||
@staticmethod
|
||||
async def get_allowed_tools_for_server(
|
||||
|
|
@ -471,8 +448,8 @@ class MCPRequestHandler:
|
|||
return None
|
||||
|
||||
try:
|
||||
# Get key and team object permissions
|
||||
key_obj_perm = await MCPRequestHandler._get_key_object_permission(
|
||||
# Get key and team object permissions (already loaded in main auth flow)
|
||||
key_obj_perm = MCPRequestHandler._get_key_object_permission(
|
||||
user_api_key_auth
|
||||
)
|
||||
team_obj_perm = await MCPRequestHandler._get_team_object_permission(
|
||||
|
|
@ -559,7 +536,8 @@ class MCPRequestHandler:
|
|||
user_api_key_auth: Optional[UserAPIKeyAuth] = None,
|
||||
) -> List[str]:
|
||||
try:
|
||||
key_object_permission = await MCPRequestHandler._get_key_object_permission(
|
||||
# Get key object permission (already loaded in main auth flow)
|
||||
key_object_permission = MCPRequestHandler._get_key_object_permission(
|
||||
user_api_key_auth
|
||||
)
|
||||
if key_object_permission is None:
|
||||
|
|
@ -591,12 +569,10 @@ class MCPRequestHandler:
|
|||
"""
|
||||
Get allowed MCP servers for a team.
|
||||
|
||||
Uses the helper _get_team_object_permission which:
|
||||
1. First checks if object_permission is already loaded on the team
|
||||
2. If not, fetches from DB using object_permission_id if it exists
|
||||
Note: object_permission is automatically loaded by get_team_object() in main auth flow.
|
||||
"""
|
||||
try:
|
||||
# Use the helper method that properly handles fetching from DB if needed
|
||||
# Get team object permission (already loaded in main auth flow)
|
||||
object_permissions = await MCPRequestHandler._get_team_object_permission(
|
||||
user_api_key_auth
|
||||
)
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
import json
|
||||
from typing import Optional
|
||||
from urllib.parse import urlencode, urlparse, urlunparse
|
||||
from urllib.parse import parse_qsl, urlencode, urlparse, urlunparse
|
||||
|
||||
from fastapi import APIRouter, Form, HTTPException, Request
|
||||
from fastapi.responses import HTMLResponse, JSONResponse, RedirectResponse
|
||||
|
|
@ -194,7 +194,13 @@ async def authorize_with_server(
|
|||
if code_challenge_method:
|
||||
params["code_challenge_method"] = code_challenge_method
|
||||
|
||||
return RedirectResponse(f"{mcp_server.authorization_url}?{urlencode(params)}")
|
||||
parsed_auth_url = urlparse(mcp_server.authorization_url)
|
||||
existing_params = dict(parse_qsl(parsed_auth_url.query))
|
||||
existing_params.update(params)
|
||||
final_url = urlunparse(
|
||||
parsed_auth_url._replace(query=urlencode(existing_params))
|
||||
)
|
||||
return RedirectResponse(final_url)
|
||||
|
||||
|
||||
async def exchange_token_with_server(
|
||||
|
|
|
|||
|
|
@ -70,9 +70,7 @@ try:
|
|||
from mcp.shared.tool_name_validation import (
|
||||
validate_tool_name, # pyright: ignore[reportAssignmentType]
|
||||
)
|
||||
from mcp.shared.tool_name_validation import (
|
||||
SEP_986_URL,
|
||||
)
|
||||
from mcp.shared.tool_name_validation import SEP_986_URL
|
||||
except ImportError:
|
||||
from pydantic import BaseModel
|
||||
|
||||
|
|
@ -673,24 +671,47 @@ class MCPServerManager:
|
|||
return [
|
||||
server.server_id
|
||||
for server in self.get_registry().values()
|
||||
if server.allow_all_keys
|
||||
if server.allow_all_keys is True
|
||||
]
|
||||
|
||||
async def get_allowed_mcp_servers(
|
||||
self, user_api_key_auth: Optional[UserAPIKeyAuth] = None
|
||||
) -> List[str]:
|
||||
"""
|
||||
Get the allowed MCP Servers for the user
|
||||
Get the allowed MCP Servers for the user.
|
||||
|
||||
Priority:
|
||||
1. If object_permission.mcp_servers is explicitly set, use it (even for admins)
|
||||
2. If admin and no object_permission, return all servers
|
||||
3. Otherwise, use standard permission checks
|
||||
"""
|
||||
from litellm.proxy.management_endpoints.common_utils import _user_has_admin_view
|
||||
|
||||
# If admin, get all servers
|
||||
if user_api_key_auth and _user_has_admin_view(user_api_key_auth):
|
||||
return list(self.get_registry().keys())
|
||||
|
||||
allow_all_server_ids = self.get_allow_all_keys_server_ids()
|
||||
|
||||
try:
|
||||
# Check if object_permission.mcp_servers is explicitly set
|
||||
has_explicit_object_permission = False
|
||||
if user_api_key_auth and user_api_key_auth.object_permission:
|
||||
# Check if mcp_servers is explicitly set (not None, empty list is valid)
|
||||
if user_api_key_auth.object_permission.mcp_servers is not None:
|
||||
has_explicit_object_permission = True
|
||||
verbose_logger.debug(
|
||||
f"Object permission mcp_servers explicitly set: {user_api_key_auth.object_permission.mcp_servers}"
|
||||
)
|
||||
|
||||
# If admin but NO explicit object permission, get all servers
|
||||
if (
|
||||
user_api_key_auth
|
||||
and _user_has_admin_view(user_api_key_auth)
|
||||
and not has_explicit_object_permission
|
||||
):
|
||||
verbose_logger.debug(
|
||||
"Admin user without explicit object_permission - returning all servers"
|
||||
)
|
||||
return list(self.get_registry().keys())
|
||||
|
||||
# Get allowed servers from object permissions (respects object_permission even for admins)
|
||||
allowed_mcp_servers = await MCPRequestHandler.get_allowed_mcp_servers(
|
||||
user_api_key_auth
|
||||
)
|
||||
|
|
@ -2246,6 +2267,7 @@ class MCPServerManager:
|
|||
from litellm.proxy.proxy_server import (
|
||||
general_settings as proxy_general_settings,
|
||||
)
|
||||
|
||||
return proxy_general_settings
|
||||
except ImportError:
|
||||
# Fallback if proxy_server not available
|
||||
|
|
|
|||
|
|
@ -37,6 +37,7 @@ if MCP_AVAILABLE:
|
|||
from litellm.proxy._experimental.mcp_server.server import (
|
||||
ListMCPToolsRestAPIResponseObject,
|
||||
MCPServer,
|
||||
_tool_name_matches,
|
||||
execute_mcp_tool,
|
||||
filter_tools_by_allowed_tools,
|
||||
)
|
||||
|
|
@ -159,6 +160,7 @@ if MCP_AVAILABLE:
|
|||
server,
|
||||
server_auth_header,
|
||||
raw_headers: Optional[Dict[str, str]] = None,
|
||||
user_api_key_auth: Optional[UserAPIKeyAuth] = None,
|
||||
):
|
||||
"""Helper function to get tools for a single server."""
|
||||
tools = await global_mcp_server_manager._get_tools_from_server(
|
||||
|
|
@ -173,6 +175,29 @@ if MCP_AVAILABLE:
|
|||
if server.allowed_tools is not None and len(server.allowed_tools) > 0:
|
||||
tools = filter_tools_by_allowed_tools(tools, server)
|
||||
|
||||
# Filter tools based on user_api_key_auth.object_permission.mcp_tool_permissions
|
||||
# This provides per-key/team/org control over which tools can be accessed
|
||||
if (
|
||||
user_api_key_auth
|
||||
and user_api_key_auth.object_permission
|
||||
and user_api_key_auth.object_permission.mcp_tool_permissions
|
||||
):
|
||||
allowed_tools_for_server = (
|
||||
user_api_key_auth.object_permission.mcp_tool_permissions.get(
|
||||
server.server_id
|
||||
)
|
||||
)
|
||||
if (
|
||||
allowed_tools_for_server is not None
|
||||
and len(allowed_tools_for_server) > 0
|
||||
):
|
||||
# Filter tools to only include those in the allowed list
|
||||
tools = [
|
||||
tool
|
||||
for tool in tools
|
||||
if _tool_name_matches(tool.name, allowed_tools_for_server)
|
||||
]
|
||||
|
||||
return _create_tool_response_objects(tools, server.mcp_info)
|
||||
|
||||
async def _resolve_allowed_mcp_servers_for_tool_call(
|
||||
|
|
@ -197,9 +222,7 @@ if MCP_AVAILABLE:
|
|||
)
|
||||
allowed_mcp_servers: List[MCPServer] = []
|
||||
for allowed_server_id in allowed_server_ids_set:
|
||||
server = global_mcp_server_manager.get_mcp_server_by_id(
|
||||
allowed_server_id
|
||||
)
|
||||
server = global_mcp_server_manager.get_mcp_server_by_id(allowed_server_id)
|
||||
if server is not None:
|
||||
allowed_mcp_servers.append(server)
|
||||
return allowed_mcp_servers
|
||||
|
|
@ -276,9 +299,7 @@ if MCP_AVAILABLE:
|
|||
"message": f"The key is not allowed to access server {server_id}",
|
||||
},
|
||||
)
|
||||
server = global_mcp_server_manager.get_mcp_server_by_id(
|
||||
server_id
|
||||
)
|
||||
server = global_mcp_server_manager.get_mcp_server_by_id(server_id)
|
||||
if server is None:
|
||||
return {
|
||||
"tools": [],
|
||||
|
|
@ -292,7 +313,10 @@ if MCP_AVAILABLE:
|
|||
|
||||
try:
|
||||
list_tools_result = await _get_tools_for_single_server(
|
||||
server, server_auth_header, raw_headers_from_request
|
||||
server,
|
||||
server_auth_header,
|
||||
raw_headers_from_request,
|
||||
user_api_key_dict,
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_logger.exception(
|
||||
|
|
@ -328,7 +352,10 @@ if MCP_AVAILABLE:
|
|||
|
||||
try:
|
||||
tools_result = await _get_tools_for_single_server(
|
||||
server, server_auth_header, raw_headers_from_request
|
||||
server,
|
||||
server_auth_header,
|
||||
raw_headers_from_request,
|
||||
user_api_key_dict,
|
||||
)
|
||||
list_tools_result.extend(tools_result)
|
||||
except Exception as e:
|
||||
|
|
|
|||
|
|
@ -420,7 +420,8 @@ class LiteLLMRoutes(enum.Enum):
|
|||
"/mcp/tools",
|
||||
"/mcp/tools/list",
|
||||
"/mcp/tools/call",
|
||||
# Read-only MCP discovery endpoint (virtual keys may be allowed here)
|
||||
"/mcp-rest/tools/list",
|
||||
"/mcp-rest/tools/call",
|
||||
"/v1/mcp/server",
|
||||
]
|
||||
|
||||
|
|
@ -632,6 +633,9 @@ class LiteLLMRoutes(enum.Enum):
|
|||
"/model/{model_id}/update",
|
||||
"/prompt/list",
|
||||
"/prompt/info",
|
||||
# Invitation routes - org/team admins checked in endpoint via _user_has_admin_privileges
|
||||
"/invitation/new",
|
||||
"/invitation/delete",
|
||||
] # routes that manage their own allowed/disallowed logic
|
||||
|
||||
## Org Admin Routes ##
|
||||
|
|
|
|||
|
|
@ -21,7 +21,7 @@ class AgentRequestHandler:
|
|||
1. Key-level agent permissions
|
||||
2. Team-level agent permissions
|
||||
3. Agent access group resolution
|
||||
|
||||
|
||||
Follows the same inheritance logic as MCP:
|
||||
- If team has restrictions and key has restrictions: use intersection
|
||||
- If team has restrictions and key has none: inherit from team
|
||||
|
|
@ -35,7 +35,7 @@ class AgentRequestHandler:
|
|||
) -> List[str]:
|
||||
"""
|
||||
Get list of allowed agent IDs for the given user/key based on permissions.
|
||||
|
||||
|
||||
Returns:
|
||||
List[str]: List of allowed agent IDs. Empty list means no restrictions (allow all).
|
||||
"""
|
||||
|
|
@ -45,7 +45,9 @@ class AgentRequestHandler:
|
|||
await AgentRequestHandler._get_allowed_agents_for_key(user_api_key_auth)
|
||||
)
|
||||
allowed_agents_for_team = (
|
||||
await AgentRequestHandler._get_allowed_agents_for_team(user_api_key_auth)
|
||||
await AgentRequestHandler._get_allowed_agents_for_team(
|
||||
user_api_key_auth
|
||||
)
|
||||
)
|
||||
|
||||
# If team has agent restrictions, handle inheritance and intersection logic
|
||||
|
|
@ -73,62 +75,48 @@ class AgentRequestHandler:
|
|||
) -> bool:
|
||||
"""
|
||||
Check if a specific agent is allowed for the given user/key.
|
||||
|
||||
|
||||
Args:
|
||||
agent_id: The agent ID to check
|
||||
user_api_key_auth: User authentication info
|
||||
|
||||
|
||||
Returns:
|
||||
bool: True if agent is allowed, False otherwise
|
||||
"""
|
||||
allowed_agents = await AgentRequestHandler.get_allowed_agents(user_api_key_auth)
|
||||
|
||||
|
||||
# Empty list means no restrictions - allow all
|
||||
if len(allowed_agents) == 0:
|
||||
return True
|
||||
|
||||
|
||||
return agent_id in allowed_agents
|
||||
|
||||
@staticmethod
|
||||
async def _get_key_object_permission(
|
||||
def _get_key_object_permission(
|
||||
user_api_key_auth: Optional[UserAPIKeyAuth] = None,
|
||||
) -> Optional[LiteLLM_ObjectPermissionTable]:
|
||||
"""Helper to get key object_permission from cache or DB."""
|
||||
from litellm.proxy.auth.auth_checks import get_object_permission
|
||||
from litellm.proxy.proxy_server import (
|
||||
prisma_client,
|
||||
proxy_logging_obj,
|
||||
user_api_key_cache,
|
||||
)
|
||||
"""
|
||||
Get key object_permission - already loaded by get_key_object() in main auth flow.
|
||||
|
||||
Note: object_permission is automatically populated when the key is fetched via
|
||||
get_key_object() in litellm/proxy/auth/auth_checks.py
|
||||
"""
|
||||
if not user_api_key_auth:
|
||||
return None
|
||||
|
||||
# Already loaded
|
||||
if user_api_key_auth.object_permission:
|
||||
return user_api_key_auth.object_permission
|
||||
|
||||
# Need to fetch from DB
|
||||
if user_api_key_auth.object_permission_id and prisma_client:
|
||||
return await get_object_permission(
|
||||
object_permission_id=user_api_key_auth.object_permission_id,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
parent_otel_span=user_api_key_auth.parent_otel_span,
|
||||
proxy_logging_obj=proxy_logging_obj,
|
||||
)
|
||||
|
||||
return None
|
||||
return user_api_key_auth.object_permission
|
||||
|
||||
@staticmethod
|
||||
async def _get_team_object_permission(
|
||||
user_api_key_auth: Optional[UserAPIKeyAuth] = None,
|
||||
) -> Optional[LiteLLM_ObjectPermissionTable]:
|
||||
"""Helper to get team object_permission from cache or DB."""
|
||||
from litellm.proxy.auth.auth_checks import (
|
||||
get_object_permission,
|
||||
get_team_object,
|
||||
)
|
||||
"""
|
||||
Get team object_permission - automatically loaded by get_team_object() in main auth flow.
|
||||
|
||||
Note: object_permission is automatically populated when the team is fetched via
|
||||
get_team_object() in litellm/proxy/auth/auth_checks.py
|
||||
"""
|
||||
from litellm.proxy.auth.auth_checks import get_team_object
|
||||
from litellm.proxy.proxy_server import (
|
||||
prisma_client,
|
||||
proxy_logging_obj,
|
||||
|
|
@ -138,7 +126,7 @@ class AgentRequestHandler:
|
|||
if not user_api_key_auth or not user_api_key_auth.team_id or not prisma_client:
|
||||
return None
|
||||
|
||||
# First get the team object (which may have object_permission already loaded)
|
||||
# Get the team object (which has object_permission already loaded)
|
||||
team_obj: Optional[LiteLLM_TeamTable] = await get_team_object(
|
||||
team_id=user_api_key_auth.team_id,
|
||||
prisma_client=prisma_client,
|
||||
|
|
@ -150,21 +138,7 @@ class AgentRequestHandler:
|
|||
if not team_obj:
|
||||
return None
|
||||
|
||||
# Already loaded
|
||||
if team_obj.object_permission:
|
||||
return team_obj.object_permission
|
||||
|
||||
# Need to fetch from DB using object_permission_id
|
||||
if team_obj.object_permission_id:
|
||||
return await get_object_permission(
|
||||
object_permission_id=team_obj.object_permission_id,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
parent_otel_span=user_api_key_auth.parent_otel_span,
|
||||
proxy_logging_obj=proxy_logging_obj,
|
||||
)
|
||||
|
||||
return None
|
||||
return team_obj.object_permission
|
||||
|
||||
@staticmethod
|
||||
async def _get_allowed_agents_for_key(
|
||||
|
|
@ -172,31 +146,16 @@ class AgentRequestHandler:
|
|||
) -> List[str]:
|
||||
"""
|
||||
Get allowed agents for a key from its object_permission.
|
||||
"""
|
||||
from litellm.proxy.auth.auth_checks import get_object_permission
|
||||
from litellm.proxy.proxy_server import (
|
||||
prisma_client,
|
||||
proxy_logging_obj,
|
||||
user_api_key_cache,
|
||||
)
|
||||
|
||||
Note: object_permission is already loaded by get_key_object() in main auth flow.
|
||||
"""
|
||||
if user_api_key_auth is None:
|
||||
return []
|
||||
|
||||
if user_api_key_auth.object_permission_id is None:
|
||||
return []
|
||||
|
||||
if prisma_client is None:
|
||||
verbose_logger.debug("prisma_client is None")
|
||||
return []
|
||||
|
||||
try:
|
||||
key_object_permission = await get_object_permission(
|
||||
object_permission_id=user_api_key_auth.object_permission_id,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
parent_otel_span=user_api_key_auth.parent_otel_span,
|
||||
proxy_logging_obj=proxy_logging_obj,
|
||||
# Get key object permission (already loaded in main auth flow)
|
||||
key_object_permission = AgentRequestHandler._get_key_object_permission(
|
||||
user_api_key_auth
|
||||
)
|
||||
if key_object_permission is None:
|
||||
return []
|
||||
|
|
@ -205,8 +164,10 @@ class AgentRequestHandler:
|
|||
direct_agents = key_object_permission.agents or []
|
||||
|
||||
# Get agents from access groups
|
||||
access_group_agents = await AgentRequestHandler._get_agents_from_access_groups(
|
||||
key_object_permission.agent_access_groups or []
|
||||
access_group_agents = (
|
||||
await AgentRequestHandler._get_agents_from_access_groups(
|
||||
key_object_permission.agent_access_groups or []
|
||||
)
|
||||
)
|
||||
|
||||
# Combine both lists
|
||||
|
|
@ -222,6 +183,8 @@ class AgentRequestHandler:
|
|||
) -> List[str]:
|
||||
"""
|
||||
Get allowed agents for a team from its object_permission.
|
||||
|
||||
Note: object_permission is already loaded by get_team_object() in main auth flow.
|
||||
"""
|
||||
if user_api_key_auth is None:
|
||||
return []
|
||||
|
|
@ -230,7 +193,7 @@ class AgentRequestHandler:
|
|||
return []
|
||||
|
||||
try:
|
||||
# Use the helper method that properly handles fetching from DB if needed
|
||||
# Get team object permission (already loaded in main auth flow)
|
||||
object_permissions = await AgentRequestHandler._get_team_object_permission(
|
||||
user_api_key_auth
|
||||
)
|
||||
|
|
@ -242,8 +205,10 @@ class AgentRequestHandler:
|
|||
direct_agents = object_permissions.agents or []
|
||||
|
||||
# Get agents from access groups
|
||||
access_group_agents = await AgentRequestHandler._get_agents_from_access_groups(
|
||||
object_permissions.agent_access_groups or []
|
||||
access_group_agents = (
|
||||
await AgentRequestHandler._get_agents_from_access_groups(
|
||||
object_permissions.agent_access_groups or []
|
||||
)
|
||||
)
|
||||
|
||||
# Combine both lists
|
||||
|
|
@ -284,9 +249,7 @@ class AgentRequestHandler:
|
|||
for agent in agents:
|
||||
agent_ids.add(agent.agent_id)
|
||||
except Exception as e:
|
||||
verbose_logger.debug(
|
||||
f"Error getting agents from access groups: {e}"
|
||||
)
|
||||
verbose_logger.debug(f"Error getting agents from access groups: {e}")
|
||||
return agent_ids
|
||||
|
||||
@staticmethod
|
||||
|
|
@ -306,16 +269,16 @@ class AgentRequestHandler:
|
|||
)
|
||||
|
||||
# Use the helper for DB agents
|
||||
db_agent_ids = await AgentRequestHandler._get_db_agent_ids_for_access_groups(
|
||||
prisma_client, access_groups
|
||||
db_agent_ids = (
|
||||
await AgentRequestHandler._get_db_agent_ids_for_access_groups(
|
||||
prisma_client, access_groups
|
||||
)
|
||||
)
|
||||
agent_ids.update(db_agent_ids)
|
||||
|
||||
return list(agent_ids)
|
||||
except Exception as e:
|
||||
verbose_logger.warning(
|
||||
f"Failed to get agents from access groups: {str(e)}"
|
||||
)
|
||||
verbose_logger.warning(f"Failed to get agents from access groups: {str(e)}")
|
||||
return []
|
||||
|
||||
@staticmethod
|
||||
|
|
@ -326,11 +289,15 @@ class AgentRequestHandler:
|
|||
Get list of agent access groups for the given user/key based on permissions.
|
||||
"""
|
||||
access_groups: List[str] = []
|
||||
access_groups_for_key = await AgentRequestHandler._get_agent_access_groups_for_key(
|
||||
user_api_key_auth
|
||||
access_groups_for_key = (
|
||||
await AgentRequestHandler._get_agent_access_groups_for_key(
|
||||
user_api_key_auth
|
||||
)
|
||||
)
|
||||
access_groups_for_team = await AgentRequestHandler._get_agent_access_groups_for_team(
|
||||
user_api_key_auth
|
||||
access_groups_for_team = (
|
||||
await AgentRequestHandler._get_agent_access_groups_for_team(
|
||||
user_api_key_auth
|
||||
)
|
||||
)
|
||||
|
||||
# If team has access groups, then key must have a subset of the team's access groups
|
||||
|
|
@ -378,7 +345,9 @@ class AgentRequestHandler:
|
|||
|
||||
return key_object_permission.agent_access_groups or []
|
||||
except Exception as e:
|
||||
verbose_logger.warning(f"Failed to get agent access groups for key: {str(e)}")
|
||||
verbose_logger.warning(
|
||||
f"Failed to get agent access groups for key: {str(e)}"
|
||||
)
|
||||
return []
|
||||
|
||||
@staticmethod
|
||||
|
|
@ -425,4 +394,3 @@ class AgentRequestHandler:
|
|||
f"Failed to get agent access groups for team: {str(e)}"
|
||||
)
|
||||
return []
|
||||
|
||||
|
|
|
|||
|
|
@ -1368,6 +1368,22 @@ async def _get_team_object_from_user_api_key_cache(
|
|||
raise Exception
|
||||
|
||||
_response = LiteLLM_TeamTableCachedObj(**response.dict())
|
||||
|
||||
# Load object_permission if object_permission_id exists but object_permission is not loaded
|
||||
if _response.object_permission_id and not _response.object_permission:
|
||||
try:
|
||||
_response.object_permission = await get_object_permission(
|
||||
object_permission_id=_response.object_permission_id,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
parent_otel_span=None,
|
||||
proxy_logging_obj=proxy_logging_obj,
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.debug(
|
||||
f"Failed to load object_permission for team {team_id} with object_permission_id={_response.object_permission_id}: {e}"
|
||||
)
|
||||
|
||||
# save the team object to cache
|
||||
await _cache_team_object(
|
||||
team_id=team_id,
|
||||
|
|
@ -1550,6 +1566,21 @@ async def get_team_object_by_alias(
|
|||
team = teams[0]
|
||||
team_obj = LiteLLM_TeamTableCachedObj(**team.model_dump())
|
||||
|
||||
# Load object_permission if object_permission_id exists but object_permission is not loaded
|
||||
if team_obj.object_permission_id and not team_obj.object_permission:
|
||||
try:
|
||||
team_obj.object_permission = await get_object_permission(
|
||||
object_permission_id=team_obj.object_permission_id,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
parent_otel_span=parent_otel_span,
|
||||
proxy_logging_obj=proxy_logging_obj,
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.debug(
|
||||
f"Failed to load object_permission for team {team_obj.team_id} with object_permission_id={team_obj.object_permission_id}: {e}"
|
||||
)
|
||||
|
||||
# Cache the result by both alias and team_id
|
||||
await user_api_key_cache.async_set_cache(
|
||||
key=cache_key,
|
||||
|
|
@ -1838,6 +1869,21 @@ async def get_key_object(
|
|||
|
||||
_response = UserAPIKeyAuth(**_valid_token.model_dump(exclude_none=True))
|
||||
|
||||
# Load object_permission if object_permission_id exists but object_permission is not loaded
|
||||
if _response.object_permission_id and not _response.object_permission:
|
||||
try:
|
||||
_response.object_permission = await get_object_permission(
|
||||
object_permission_id=_response.object_permission_id,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
parent_otel_span=parent_otel_span,
|
||||
proxy_logging_obj=proxy_logging_obj,
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.debug(
|
||||
f"Failed to load object_permission for key with object_permission_id={_response.object_permission_id}: {e}"
|
||||
)
|
||||
|
||||
# save the key object to cache
|
||||
await _cache_key_object(
|
||||
hashed_token=hashed_token,
|
||||
|
|
|
|||
|
|
@ -394,6 +394,14 @@ def get_logging_caching_headers(request_data: Dict) -> Optional[Dict]:
|
|||
_metadata["applied_policies"]
|
||||
)
|
||||
|
||||
if "policy_sources" in _metadata:
|
||||
sources = _metadata["policy_sources"]
|
||||
if isinstance(sources, dict) and sources:
|
||||
# Use ';' as delimiter — matched_via reasons may contain commas
|
||||
headers["x-litellm-policy-sources"] = "; ".join(
|
||||
f"{name}={reason}" for name, reason in sources.items()
|
||||
)
|
||||
|
||||
if "semantic-similarity" in _metadata:
|
||||
headers["x-litellm-semantic-similarity"] = str(_metadata["semantic-similarity"])
|
||||
|
||||
|
|
@ -441,6 +449,27 @@ def add_policy_to_applied_policies_header(
|
|||
request_data["metadata"] = _metadata
|
||||
|
||||
|
||||
def add_policy_sources_to_metadata(
|
||||
request_data: Dict, policy_sources: Dict[str, str]
|
||||
):
|
||||
"""
|
||||
Store policy match reasons in metadata for x-litellm-policy-sources header.
|
||||
|
||||
Args:
|
||||
request_data: The request data dict
|
||||
policy_sources: Map of policy_name -> matched_via reason
|
||||
"""
|
||||
if not policy_sources:
|
||||
return
|
||||
_metadata = request_data.get("metadata", None) or {}
|
||||
existing = _metadata.get("policy_sources", {})
|
||||
if not isinstance(existing, dict):
|
||||
existing = {}
|
||||
existing.update(policy_sources)
|
||||
_metadata["policy_sources"] = existing
|
||||
request_data["metadata"] = _metadata
|
||||
|
||||
|
||||
def add_guardrail_response_to_standard_logging_object(
|
||||
litellm_logging_obj: Optional["LiteLLMLogging"],
|
||||
guardrail_response: StandardLoggingGuardrailInformation,
|
||||
|
|
|
|||
|
|
@ -10,14 +10,18 @@ from litellm._service_logger import ServiceLogging
|
|||
service_logger_obj = (
|
||||
ServiceLogging()
|
||||
) # used for tracking metrics for In memory buffer, redis buffer, pod lock manager
|
||||
from litellm.constants import MAX_IN_MEMORY_QUEUE_FLUSH_COUNT, MAX_SIZE_IN_MEMORY_QUEUE
|
||||
from litellm.constants import (
|
||||
LITELLM_ASYNCIO_QUEUE_MAXSIZE,
|
||||
MAX_IN_MEMORY_QUEUE_FLUSH_COUNT,
|
||||
MAX_SIZE_IN_MEMORY_QUEUE,
|
||||
)
|
||||
|
||||
|
||||
class BaseUpdateQueue:
|
||||
"""Base class for in memory buffer for database transactions"""
|
||||
|
||||
def __init__(self):
|
||||
self.update_queue = asyncio.Queue()
|
||||
self.update_queue = asyncio.Queue(maxsize=LITELLM_ASYNCIO_QUEUE_MAXSIZE)
|
||||
self.MAX_SIZE_IN_MEMORY_QUEUE = MAX_SIZE_IN_MEMORY_QUEUE
|
||||
|
||||
async def add_update(self, update):
|
||||
|
|
|
|||
|
|
@ -3,6 +3,7 @@ from copy import deepcopy
|
|||
from typing import Dict, List, Optional
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.constants import LITELLM_ASYNCIO_QUEUE_MAXSIZE
|
||||
from litellm.proxy._types import BaseDailySpendTransaction
|
||||
from litellm.proxy.db.db_transaction_queue.base_update_queue import (
|
||||
BaseUpdateQueue,
|
||||
|
|
@ -54,7 +55,7 @@ class DailySpendUpdateQueue(BaseUpdateQueue):
|
|||
def __init__(self):
|
||||
super().__init__()
|
||||
self.update_queue: asyncio.Queue[Dict[str, BaseDailySpendTransaction]] = (
|
||||
asyncio.Queue()
|
||||
asyncio.Queue(maxsize=LITELLM_ASYNCIO_QUEUE_MAXSIZE)
|
||||
)
|
||||
|
||||
async def add_update(self, update: Dict[str, BaseDailySpendTransaction]):
|
||||
|
|
|
|||
|
|
@ -2,6 +2,7 @@ import asyncio
|
|||
from typing import Dict, List, Optional
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.constants import LITELLM_ASYNCIO_QUEUE_MAXSIZE
|
||||
from litellm.proxy._types import (
|
||||
DBSpendUpdateTransactions,
|
||||
Litellm_EntityType,
|
||||
|
|
@ -21,7 +22,9 @@ class SpendUpdateQueue(BaseUpdateQueue):
|
|||
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.update_queue: asyncio.Queue[SpendUpdateQueueItem] = asyncio.Queue()
|
||||
self.update_queue: asyncio.Queue[SpendUpdateQueueItem] = asyncio.Queue(
|
||||
maxsize=LITELLM_ASYNCIO_QUEUE_MAXSIZE
|
||||
)
|
||||
|
||||
async def flush_and_get_aggregated_db_spend_update_transactions(
|
||||
self,
|
||||
|
|
|
|||
|
|
@ -19,13 +19,15 @@ async def get_ui_config():
|
|||
from litellm.proxy.utils import get_proxy_base_url, get_server_root_path
|
||||
|
||||
auto_redirect_ui_login_to_sso = (
|
||||
os.getenv("AUTO_REDIRECT_UI_LOGIN_TO_SSO", "true").lower() == "true"
|
||||
os.getenv("AUTO_REDIRECT_UI_LOGIN_TO_SSO", "false").lower() == "true"
|
||||
)
|
||||
admin_ui_disabled = os.getenv("DISABLE_ADMIN_UI", "false").lower() == "true"
|
||||
|
||||
sso_configured = _has_user_setup_sso()
|
||||
return UiDiscoveryEndpoints(
|
||||
server_root_path=get_server_root_path(),
|
||||
proxy_base_url=get_proxy_base_url(),
|
||||
auto_redirect_to_sso=_has_user_setup_sso() and auto_redirect_ui_login_to_sso,
|
||||
auto_redirect_to_sso=sso_configured and auto_redirect_ui_login_to_sso,
|
||||
admin_ui_disabled=admin_ui_disabled,
|
||||
sso_configured=sso_configured,
|
||||
)
|
||||
|
|
|
|||
File diff suppressed because it is too large
Load diff
|
|
@ -6,6 +6,7 @@ to detect and block/mask sensitive content.
|
|||
"""
|
||||
|
||||
import asyncio
|
||||
import json
|
||||
import os
|
||||
import re
|
||||
from datetime import datetime
|
||||
|
|
@ -150,6 +151,7 @@ class ContentFilterGuardrail(CustomGuardrail):
|
|||
categories: List of category configurations with enabled/action/severity settings
|
||||
severity_threshold: Minimum severity to block ("high", "medium", "low")
|
||||
"""
|
||||
|
||||
super().__init__(
|
||||
guardrail_name=guardrail_name,
|
||||
supported_event_hooks=[
|
||||
|
|
@ -179,6 +181,12 @@ class ContentFilterGuardrail(CustomGuardrail):
|
|||
# Load categories if provided
|
||||
if categories:
|
||||
self._load_categories(categories)
|
||||
else:
|
||||
verbose_proxy_logger.warning(
|
||||
"ContentFilterGuardrail has no content categories configured. "
|
||||
"Toxic/abuse and other category-based keyword filtering will not run. "
|
||||
"Add categories (e.g. harm_toxic_abuse) in the guardrail config to enable them."
|
||||
)
|
||||
|
||||
# Normalize inputs: convert dicts to Pydantic models for consistent handling
|
||||
normalized_patterns: List[ContentFilterPattern] = []
|
||||
|
|
@ -276,9 +284,15 @@ class ContentFilterGuardrail(CustomGuardrail):
|
|||
if custom_file:
|
||||
category_file_path = custom_file
|
||||
else:
|
||||
category_file_path = os.path.join(
|
||||
categories_dir, f"{category_name}.yaml"
|
||||
)
|
||||
# Try .yaml first, then .json (e.g. harm_toxic_abuse.json)
|
||||
yaml_path = os.path.join(categories_dir, f"{category_name}.yaml")
|
||||
json_path = os.path.join(categories_dir, f"{category_name}.json")
|
||||
if os.path.exists(yaml_path):
|
||||
category_file_path = yaml_path
|
||||
elif os.path.exists(json_path):
|
||||
category_file_path = json_path
|
||||
else:
|
||||
category_file_path = yaml_path # will trigger "not found" below
|
||||
|
||||
if not os.path.exists(category_file_path):
|
||||
verbose_proxy_logger.warning(
|
||||
|
|
@ -319,17 +333,23 @@ class ContentFilterGuardrail(CustomGuardrail):
|
|||
|
||||
def _load_category_file(self, file_path: str) -> CategoryConfig:
|
||||
"""
|
||||
Load a category definition from a YAML file.
|
||||
Load a category definition from a YAML or JSON file.
|
||||
|
||||
YAML format: category_name, description, default_action, keywords (list of
|
||||
{keyword, severity}), exceptions.
|
||||
JSON format: list of {id, match, tags, severity}; match is pipe-separated
|
||||
phrases; severity 1-4 mapped to low/medium/high. Used for harm_toxic_abuse.
|
||||
|
||||
Args:
|
||||
file_path: Path to category YAML file
|
||||
file_path: Path to category YAML or JSON file
|
||||
|
||||
Returns:
|
||||
CategoryConfig object
|
||||
"""
|
||||
if file_path.lower().endswith(".json"):
|
||||
return self._load_category_file_json(file_path)
|
||||
with open(file_path, "r") as f:
|
||||
data = yaml.safe_load(f)
|
||||
|
||||
return CategoryConfig(
|
||||
category_name=data.get("category_name", "unknown"),
|
||||
description=data.get("description", ""),
|
||||
|
|
@ -338,6 +358,44 @@ class ContentFilterGuardrail(CustomGuardrail):
|
|||
exceptions=data.get("exceptions", []),
|
||||
)
|
||||
|
||||
def _load_category_file_json(self, file_path: str) -> CategoryConfig:
|
||||
"""
|
||||
Load a category from the harm_toxic_abuse-style JSON format.
|
||||
|
||||
Each entry has: id, match (pipe-separated phrases), tags, severity (1-4).
|
||||
Severity mapping: 4,3 -> high; 2 -> medium; 1 -> low.
|
||||
"""
|
||||
with open(file_path, "r") as f:
|
||||
entries = json.load(f)
|
||||
if not isinstance(entries, list):
|
||||
entries = [entries]
|
||||
# Derive category name from filename (e.g. harm_toxic_abuse.json -> harm_toxic_abuse)
|
||||
category_name = os.path.splitext(os.path.basename(file_path))[0]
|
||||
severity_map = {4: "high", 3: "high", 2: "medium", 1: "low"}
|
||||
keywords: List[Dict[str, str]] = []
|
||||
seen = set()
|
||||
for item in entries:
|
||||
if not isinstance(item, dict):
|
||||
continue
|
||||
match_str = item.get("match") or ""
|
||||
raw_severity = item.get("severity", 2)
|
||||
severity = severity_map.get(
|
||||
raw_severity if isinstance(raw_severity, int) else 2, "medium"
|
||||
)
|
||||
for phrase in match_str.split("|"):
|
||||
phrase = phrase.strip().lower()
|
||||
if not phrase or phrase in seen:
|
||||
continue
|
||||
seen.add(phrase)
|
||||
keywords.append({"keyword": phrase, "severity": severity})
|
||||
return CategoryConfig(
|
||||
category_name=category_name,
|
||||
description="Detects harmful, toxic, or abusive language and content",
|
||||
default_action=ContentFilterAction("BLOCK"),
|
||||
keywords=keywords,
|
||||
exceptions=[],
|
||||
)
|
||||
|
||||
def _should_apply_severity(self, severity: str, threshold: str) -> bool:
|
||||
"""
|
||||
Check if a given severity meets the threshold.
|
||||
|
|
|
|||
|
|
@ -139,6 +139,9 @@ def get_available_content_categories() -> List[Dict[str, str]]:
|
|||
"""
|
||||
Return available content categories for UI display.
|
||||
|
||||
Includes categories defined in .yaml/.yml files and in .json files
|
||||
(e.g. harm_toxic_abuse.json).
|
||||
|
||||
Returns:
|
||||
List of dictionaries containing category name, display_name, and description
|
||||
"""
|
||||
|
|
@ -177,6 +180,28 @@ def get_available_content_categories() -> List[Dict[str, str]]:
|
|||
except Exception:
|
||||
# Skip files that can't be loaded
|
||||
continue
|
||||
elif filename.endswith(".json"):
|
||||
# JSON category files (e.g. harm_toxic_abuse.json) - no YAML header, use filename
|
||||
category_name = os.path.splitext(filename)[0]
|
||||
try:
|
||||
if category_name == "harm_toxic_abuse":
|
||||
display_name = "Harmful Toxic Abuse"
|
||||
description = (
|
||||
"Detects harmful, toxic, or abusive language and content"
|
||||
)
|
||||
else:
|
||||
display_name = category_name.replace("_", " ").title()
|
||||
description = f"Content category: {display_name}"
|
||||
available_categories.append(
|
||||
{
|
||||
"name": category_name,
|
||||
"display_name": display_name,
|
||||
"description": description,
|
||||
"default_action": "BLOCK",
|
||||
}
|
||||
)
|
||||
except Exception:
|
||||
continue
|
||||
|
||||
# Sort by name for consistent ordering
|
||||
available_categories.sort(key=lambda x: x["name"])
|
||||
|
|
|
|||
|
|
@ -38,7 +38,7 @@ if TYPE_CHECKING:
|
|||
|
||||
from litellm._uuid import uuid
|
||||
from litellm.caching.caching import DualCache
|
||||
from litellm.exceptions import BlockedPiiEntityError
|
||||
from litellm.exceptions import BlockedPiiEntityError, GuardrailRaisedException
|
||||
from litellm.integrations.custom_guardrail import (
|
||||
CustomGuardrail,
|
||||
log_guardrail_information,
|
||||
|
|
@ -232,6 +232,14 @@ class _OPTIONAL_PresidioPIIMasking(CustomGuardrail):
|
|||
"""Cleanup: we try to close, but doing async cleanup in __del__ is risky."""
|
||||
pass
|
||||
|
||||
def _has_block_action(self) -> bool:
|
||||
"""Return True if pii_entities_config has any BLOCK action (fail-closed on analyzer errors)."""
|
||||
if not self.pii_entities_config:
|
||||
return False
|
||||
return any(
|
||||
action == PiiAction.BLOCK for action in self.pii_entities_config.values()
|
||||
)
|
||||
|
||||
def _get_presidio_analyze_request_payload(
|
||||
self,
|
||||
text: str,
|
||||
|
|
@ -316,13 +324,30 @@ class _OPTIONAL_PresidioPIIMasking(CustomGuardrail):
|
|||
|
||||
# Handle error responses from Presidio (e.g., {'error': 'No text provided'})
|
||||
# Presidio may return a dict instead of a list when errors occur
|
||||
def _fail_on_invalid_response(
|
||||
reason: str,
|
||||
) -> List[PresidioAnalyzeResponseItem]:
|
||||
should_fail_closed = (
|
||||
bool(self.pii_entities_config)
|
||||
or self.output_parse_pii
|
||||
or self.apply_to_output
|
||||
)
|
||||
if should_fail_closed:
|
||||
raise GuardrailRaisedException(
|
||||
guardrail_name=self.guardrail_name,
|
||||
message=f"Presidio analyzer returned invalid response; cannot verify PII when PII protection is configured: {reason}",
|
||||
should_wrap_with_default_message=False,
|
||||
)
|
||||
verbose_proxy_logger.warning(
|
||||
"Presidio analyzer %s, returning empty list", reason
|
||||
)
|
||||
return []
|
||||
|
||||
if isinstance(analyze_results, dict):
|
||||
if "error" in analyze_results:
|
||||
verbose_proxy_logger.warning(
|
||||
"Presidio analyzer returned error: %s, returning empty list",
|
||||
analyze_results.get("error"),
|
||||
return _fail_on_invalid_response(
|
||||
f"error: {analyze_results.get('error')}"
|
||||
)
|
||||
return []
|
||||
# If it's a dict but not an error, try to process it as a single item
|
||||
verbose_proxy_logger.debug(
|
||||
"Presidio returned dict (not list), attempting to process as single item"
|
||||
|
|
@ -330,23 +355,33 @@ class _OPTIONAL_PresidioPIIMasking(CustomGuardrail):
|
|||
try:
|
||||
return [PresidioAnalyzeResponseItem(**analyze_results)]
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.warning(
|
||||
"Failed to parse Presidio dict response: %s, returning empty list",
|
||||
e,
|
||||
return _fail_on_invalid_response(
|
||||
f"failed to parse dict response: {e}"
|
||||
)
|
||||
return []
|
||||
|
||||
# Handle unexpected types (str, None, etc.) - e.g. from malformed/error
|
||||
if not isinstance(analyze_results, list):
|
||||
return _fail_on_invalid_response(
|
||||
f"unexpected type {type(analyze_results).__name__} (expected list or dict), response: {str(analyze_results)[:200]}"
|
||||
)
|
||||
|
||||
# Normal case: list of results
|
||||
final_results = []
|
||||
for item in analyze_results:
|
||||
if not isinstance(item, dict):
|
||||
verbose_proxy_logger.warning(
|
||||
"Skipping invalid Presidio result item (expected dict, got %s): %s",
|
||||
type(item).__name__,
|
||||
str(item)[:100],
|
||||
)
|
||||
continue
|
||||
try:
|
||||
final_results.append(PresidioAnalyzeResponseItem(**item))
|
||||
except TypeError as te:
|
||||
# Handle case where item is not a dict (shouldn't happen, but be defensive)
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.warning(
|
||||
"Skipping invalid Presidio result item: %s (error: %s)",
|
||||
"Failed to parse Presidio result item: %s (error: %s)",
|
||||
item,
|
||||
te,
|
||||
e,
|
||||
)
|
||||
continue
|
||||
return final_results
|
||||
|
|
|
|||
|
|
@ -150,15 +150,26 @@ class KeyManagementEventHooks:
|
|||
existing_key_row.key_alias
|
||||
or f"virtual-key-{existing_key_row.token}"
|
||||
)
|
||||
new_secret_name = (
|
||||
response.key_alias
|
||||
or data.key_alias
|
||||
or f"virtual-key-{response.token_id}"
|
||||
)
|
||||
verbose_proxy_logger.info(
|
||||
"Updating secret in secret manager: secret_name=%s",
|
||||
new_secret_name,
|
||||
)
|
||||
team_id = getattr(existing_key_row, "team_id", None)
|
||||
await KeyManagementEventHooks._rotate_virtual_key_in_secret_manager(
|
||||
current_secret_name=initial_secret_name,
|
||||
new_secret_name=response.key_alias
|
||||
or data.key_alias
|
||||
or f"virtual-key-{response.token_id}",
|
||||
new_secret_name=new_secret_name,
|
||||
new_secret_value=response.key,
|
||||
team_id=team_id,
|
||||
)
|
||||
verbose_proxy_logger.info(
|
||||
"Secret updated in secret manager: secret_name=%s",
|
||||
new_secret_name,
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.warning(
|
||||
f"Failed to rotate virtual key in secret manager: {e}"
|
||||
|
|
|
|||
|
|
@ -153,7 +153,10 @@ class _PROXY_VirtualKeyModelMaxBudgetLimiter(RouterBudgetLimiting):
|
|||
"standard_logging_object", None
|
||||
)
|
||||
if standard_logging_payload is None:
|
||||
raise ValueError("standard_logging_payload is required")
|
||||
verbose_proxy_logger.debug(
|
||||
"Skipping _PROXY_VirtualKeyModelMaxBudgetLimiter.async_log_success_event: standard_logging_payload is None"
|
||||
)
|
||||
return
|
||||
|
||||
_litellm_params: dict = kwargs.get("litellm_params", {}) or {}
|
||||
_metadata: dict = _litellm_params.get("metadata", {}) or {}
|
||||
|
|
|
|||
|
|
@ -144,6 +144,12 @@ async def image_generation(
|
|||
litellm_call_id=data.get("litellm_call_id", ""), status="success"
|
||||
)
|
||||
)
|
||||
|
||||
### CALL HOOKS ### - modify outgoing data (guardrails, otel, etc.)
|
||||
response = await proxy_logging_obj.post_call_success_hook(
|
||||
data=data, user_api_key_dict=user_api_key_dict, response=response
|
||||
)
|
||||
|
||||
### RESPONSE HEADERS ###
|
||||
hidden_params = getattr(response, "_hidden_params", {}) or {}
|
||||
model_id = hidden_params.get("model_id", None) or ""
|
||||
|
|
|
|||
|
|
@ -1539,8 +1539,15 @@ def add_guardrails_from_policy_engine(
|
|||
"""
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.proxy.common_utils.callback_utils import (
|
||||
add_policy_sources_to_metadata,
|
||||
add_policy_to_applied_policies_header,
|
||||
)
|
||||
from litellm.proxy.common_utils.http_parsing_utils import (
|
||||
get_tags_from_request_body,
|
||||
)
|
||||
from litellm.proxy.policy_engine.attachment_registry import (
|
||||
get_attachment_registry,
|
||||
)
|
||||
from litellm.proxy.policy_engine.policy_matcher import PolicyMatcher
|
||||
from litellm.proxy.policy_engine.policy_registry import get_policy_registry
|
||||
from litellm.proxy.policy_engine.policy_resolver import PolicyResolver
|
||||
|
|
@ -1561,20 +1568,31 @@ def add_guardrails_from_policy_engine(
|
|||
)
|
||||
return
|
||||
|
||||
# Build context from request
|
||||
# Extract tags using the shared helper (handles metadata / litellm_metadata,
|
||||
# top-level tags, deduplication, and type filtering).
|
||||
|
||||
all_tags = get_tags_from_request_body(data) or None
|
||||
|
||||
context = PolicyMatchContext(
|
||||
team_alias=user_api_key_dict.team_alias,
|
||||
key_alias=user_api_key_dict.key_alias,
|
||||
model=data.get("model"),
|
||||
tags=all_tags,
|
||||
)
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
f"Policy engine: matching policies for context team_alias={context.team_alias}, "
|
||||
f"key_alias={context.key_alias}, model={context.model}"
|
||||
f"key_alias={context.key_alias}, model={context.model}, tags={context.tags}"
|
||||
)
|
||||
|
||||
# Get matching policies via attachments
|
||||
matching_policy_names = PolicyMatcher.get_matching_policies(context=context)
|
||||
# Get matching policies via attachments (with match reasons for attribution)
|
||||
attachment_registry = get_attachment_registry()
|
||||
matches_with_reasons = attachment_registry.get_attached_policies_with_reasons(
|
||||
context
|
||||
)
|
||||
matching_policy_names = [m["policy_name"] for m in matches_with_reasons]
|
||||
# Build reasons map: {"hipaa-policy": "tag:healthcare", ...}
|
||||
policy_reasons = {m["policy_name"]: m["matched_via"] for m in matches_with_reasons}
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
f"Policy engine: matched policies via attachments: {matching_policy_names}"
|
||||
|
|
@ -1607,6 +1625,16 @@ def add_guardrails_from_policy_engine(
|
|||
request_data=data, policy_name=policy_name
|
||||
)
|
||||
|
||||
# Track policy attribution sources for x-litellm-policy-sources header
|
||||
applied_reasons = {
|
||||
name: policy_reasons[name]
|
||||
for name in applied_policy_names
|
||||
if name in policy_reasons
|
||||
}
|
||||
add_policy_sources_to_metadata(
|
||||
request_data=data, policy_sources=applied_reasons
|
||||
)
|
||||
|
||||
# Resolve guardrails from matching policies
|
||||
resolved_guardrails = PolicyResolver.resolve_guardrails_for_context(context=context)
|
||||
|
||||
|
|
|
|||
|
|
@ -8,6 +8,7 @@ from litellm.proxy._types import (
|
|||
LiteLLM_ManagementEndpoint_MetadataFields_Premium,
|
||||
LiteLLM_OrganizationTable,
|
||||
LiteLLM_TeamTable,
|
||||
LiteLLM_UserTable,
|
||||
LitellmUserRoles,
|
||||
UserAPIKeyAuth,
|
||||
)
|
||||
|
|
@ -108,6 +109,154 @@ async def _user_has_admin_privileges(
|
|||
return False
|
||||
|
||||
|
||||
def _org_admin_can_invite_user(
|
||||
admin_user_obj: LiteLLM_UserTable,
|
||||
target_user_obj: LiteLLM_UserTable,
|
||||
) -> bool:
|
||||
"""
|
||||
Check if an org admin can invite the target user.
|
||||
Target user must be in at least one org where the admin has org admin role.
|
||||
|
||||
Args:
|
||||
admin_user_obj: The admin user's full object (from get_user_object)
|
||||
target_user_obj: The target user's full object (from get_user_object)
|
||||
|
||||
Returns:
|
||||
True if target user is in an org where admin has org admin role
|
||||
"""
|
||||
if admin_user_obj.organization_memberships is None:
|
||||
return False
|
||||
admin_org_ids = {
|
||||
m.organization_id
|
||||
for m in admin_user_obj.organization_memberships
|
||||
if m.user_role == LitellmUserRoles.ORG_ADMIN.value
|
||||
}
|
||||
if not admin_org_ids:
|
||||
return False
|
||||
if target_user_obj.organization_memberships is None:
|
||||
return False
|
||||
target_org_ids = {
|
||||
m.organization_id for m in target_user_obj.organization_memberships
|
||||
}
|
||||
return bool(admin_org_ids & target_org_ids)
|
||||
|
||||
|
||||
async def _team_admin_can_invite_user(
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
admin_user_obj: LiteLLM_UserTable,
|
||||
target_user_obj: LiteLLM_UserTable,
|
||||
prisma_client: "PrismaClient",
|
||||
) -> bool:
|
||||
"""
|
||||
Check if a team admin can invite the target user.
|
||||
Target user must be in at least one team where the admin has team admin role.
|
||||
|
||||
Args:
|
||||
user_api_key_dict: The admin user's API key auth object
|
||||
admin_user_obj: The admin user's full object (from get_user_object)
|
||||
target_user_obj: The target user's full object (from get_user_object)
|
||||
prisma_client: Prisma client for database operations
|
||||
|
||||
Returns:
|
||||
True if target user is in a team where admin has team admin role
|
||||
"""
|
||||
if not admin_user_obj.teams or len(admin_user_obj.teams) == 0:
|
||||
return False
|
||||
if not target_user_obj.teams or len(target_user_obj.teams) == 0:
|
||||
return False
|
||||
|
||||
teams = await prisma_client.db.litellm_teamtable.find_many(
|
||||
where={"team_id": {"in": admin_user_obj.teams}}
|
||||
)
|
||||
admin_team_ids = [
|
||||
team.team_id
|
||||
for team in teams
|
||||
if _is_user_team_admin(
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
team_obj=LiteLLM_TeamTable(**team.model_dump()),
|
||||
)
|
||||
]
|
||||
if not admin_team_ids:
|
||||
return False
|
||||
target_team_ids = set(target_user_obj.teams)
|
||||
return bool(set(admin_team_ids) & target_team_ids)
|
||||
|
||||
|
||||
async def admin_can_invite_user(
|
||||
target_user_id: str,
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
prisma_client: Optional["PrismaClient"] = None,
|
||||
user_api_key_cache: Optional["DualCache"] = None,
|
||||
proxy_logging_obj: Optional["ProxyLogging"] = None,
|
||||
) -> bool:
|
||||
"""
|
||||
Check if the admin can create an invitation for the target user.
|
||||
- Proxy admins: can invite any user
|
||||
- Org admins: can only invite users in their org(s)
|
||||
- Team admins: can only invite users in their team(s)
|
||||
|
||||
Uses get_user_object for caching of both admin and target user objects.
|
||||
|
||||
Args:
|
||||
target_user_id: The user_id of the user to invite
|
||||
user_api_key_dict: The admin user's API key auth object
|
||||
prisma_client: Prisma client for database operations
|
||||
user_api_key_cache: Cache for user API keys
|
||||
proxy_logging_obj: Proxy logging object
|
||||
|
||||
Returns:
|
||||
True if user can invite the target user
|
||||
"""
|
||||
if user_api_key_dict.user_role == LitellmUserRoles.PROXY_ADMIN:
|
||||
return True
|
||||
|
||||
if prisma_client is None or user_api_key_dict.user_id is None:
|
||||
return False
|
||||
|
||||
from litellm.caching import DualCache as DualCacheImport
|
||||
from litellm.proxy.auth.auth_checks import get_user_object
|
||||
|
||||
try:
|
||||
cache = user_api_key_cache or DualCacheImport()
|
||||
admin_user_obj = await get_user_object(
|
||||
user_id=user_api_key_dict.user_id,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=cache,
|
||||
user_id_upsert=False,
|
||||
proxy_logging_obj=proxy_logging_obj,
|
||||
)
|
||||
if admin_user_obj is None:
|
||||
return False
|
||||
|
||||
target_user_obj = await get_user_object(
|
||||
user_id=target_user_id,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=cache,
|
||||
user_id_upsert=False,
|
||||
proxy_logging_obj=proxy_logging_obj,
|
||||
)
|
||||
if target_user_obj is None:
|
||||
return False
|
||||
|
||||
if _org_admin_can_invite_user(admin_user_obj, target_user_obj):
|
||||
return True
|
||||
|
||||
if await _team_admin_can_invite_user(
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
admin_user_obj=admin_user_obj,
|
||||
target_user_obj=target_user_obj,
|
||||
prisma_client=prisma_client,
|
||||
):
|
||||
return True
|
||||
|
||||
return False
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.debug(
|
||||
f"Error checking invite permission for user {user_api_key_dict.user_id}: {e}"
|
||||
)
|
||||
return False
|
||||
|
||||
|
||||
def _set_object_metadata_field(
|
||||
object_data: Union[
|
||||
LiteLLM_TeamTable,
|
||||
|
|
|
|||
|
|
@ -2770,6 +2770,7 @@ async def can_modify_verification_token(
|
|||
|
||||
Rules:
|
||||
- Proxy admin can modify any key
|
||||
- Internal jobs service account can modify any key (for auto-rotation)
|
||||
- For team keys: only team admin or key owner can modify
|
||||
- For personal keys: only key owner can modify
|
||||
|
||||
|
|
@ -2782,13 +2783,19 @@ async def can_modify_verification_token(
|
|||
Returns:
|
||||
True if user can modify the key, False otherwise
|
||||
"""
|
||||
from litellm.constants import LITELLM_INTERNAL_JOBS_SERVICE_ACCOUNT_NAME
|
||||
|
||||
is_team_key = _is_team_key(data=key_info)
|
||||
|
||||
# 1. Proxy admin can modify any key
|
||||
if user_api_key_dict.user_role == LitellmUserRoles.PROXY_ADMIN.value:
|
||||
return True
|
||||
|
||||
# 2. For team keys: only team admin or key owner can modify
|
||||
# 2. Internal jobs service account can modify any key (for auto-rotation)
|
||||
if user_api_key_dict.api_key == LITELLM_INTERNAL_JOBS_SERVICE_ACCOUNT_NAME:
|
||||
return True
|
||||
|
||||
# 3. For team keys: only team admin or key owner can modify
|
||||
if is_team_key and key_info.team_id is not None:
|
||||
# Get team object to check if user is team admin
|
||||
team_table = await get_team_object(
|
||||
|
|
@ -2818,7 +2825,7 @@ async def can_modify_verification_token(
|
|||
# Not team admin and doesn't own the key
|
||||
return False
|
||||
|
||||
# 3. For personal keys: only key owner can modify
|
||||
# 4. For personal keys: only key owner can modify
|
||||
if key_info.user_id is not None and key_info.user_id == user_api_key_dict.user_id:
|
||||
return True
|
||||
|
||||
|
|
@ -3179,7 +3186,7 @@ def get_new_token(data: Optional[RegenerateKeyRequest]) -> str:
|
|||
dependencies=[Depends(user_api_key_auth)],
|
||||
)
|
||||
@management_endpoint_wrapper
|
||||
async def regenerate_key_fn(
|
||||
async def regenerate_key_fn( # noqa: PLR0915
|
||||
key: Optional[str] = None,
|
||||
data: Optional[RegenerateKeyRequest] = None,
|
||||
user_api_key_dict: UserAPIKeyAuth = Depends(user_api_key_auth),
|
||||
|
|
@ -3330,6 +3337,10 @@ async def regenerate_key_fn(
|
|||
detail={"error": "You are not authorized to regenerate this key"},
|
||||
)
|
||||
|
||||
verbose_proxy_logger.info(
|
||||
"Key regeneration requested: key_alias=%s",
|
||||
getattr(_key_in_db, "key_alias", None),
|
||||
)
|
||||
verbose_proxy_logger.debug("key_in_db: %s", _key_in_db)
|
||||
|
||||
new_token = get_new_token(data=data)
|
||||
|
|
@ -3380,6 +3391,10 @@ async def regenerate_key_fn(
|
|||
**updated_token_dict,
|
||||
)
|
||||
|
||||
verbose_proxy_logger.info(
|
||||
"Key regeneration completed: key_alias=%s",
|
||||
getattr(_key_in_db, "key_alias", None),
|
||||
)
|
||||
asyncio.create_task(
|
||||
KeyManagementEventHooks.async_key_rotated_hook(
|
||||
data=data,
|
||||
|
|
|
|||
|
|
@ -84,6 +84,7 @@ class AttachmentRegistry:
|
|||
teams=attachment_data.get("teams"),
|
||||
keys=attachment_data.get("keys"),
|
||||
models=attachment_data.get("models"),
|
||||
tags=attachment_data.get("tags"),
|
||||
)
|
||||
|
||||
def get_attached_policies(self, context: PolicyMatchContext) -> List[str]:
|
||||
|
|
@ -96,21 +97,68 @@ class AttachmentRegistry:
|
|||
Returns:
|
||||
List of policy names that are attached to matching scopes
|
||||
"""
|
||||
return [r["policy_name"] for r in self.get_attached_policies_with_reasons(context)]
|
||||
|
||||
def get_attached_policies_with_reasons(
|
||||
self, context: PolicyMatchContext
|
||||
) -> List[Dict[str, Any]]:
|
||||
"""
|
||||
Get list of policy names and match reasons for the given context.
|
||||
|
||||
Returns a list of dicts with 'policy_name' and 'matched_via' keys.
|
||||
The 'matched_via' describes which dimension caused the match.
|
||||
"""
|
||||
from litellm.proxy.policy_engine.policy_matcher import PolicyMatcher
|
||||
|
||||
attached_policies: List[str] = []
|
||||
results: List[Dict[str, Any]] = []
|
||||
seen_policies: set = set()
|
||||
|
||||
for attachment in self._attachments:
|
||||
scope = attachment.to_policy_scope()
|
||||
if PolicyMatcher.scope_matches(scope=scope, context=context):
|
||||
if attachment.policy not in attached_policies:
|
||||
attached_policies.append(attachment.policy)
|
||||
if attachment.policy not in seen_policies:
|
||||
seen_policies.add(attachment.policy)
|
||||
matched_via = self._describe_match_reason(attachment, context)
|
||||
results.append(
|
||||
{
|
||||
"policy_name": attachment.policy,
|
||||
"matched_via": matched_via,
|
||||
}
|
||||
)
|
||||
verbose_proxy_logger.debug(
|
||||
f"Attachment matched: policy={attachment.policy}, "
|
||||
f"matched_via={matched_via}, "
|
||||
f"context=(team={context.team_alias}, key={context.key_alias}, model={context.model})"
|
||||
)
|
||||
|
||||
return attached_policies
|
||||
return results
|
||||
|
||||
@staticmethod
|
||||
def _describe_match_reason(
|
||||
attachment: PolicyAttachment, context: PolicyMatchContext
|
||||
) -> str:
|
||||
"""Describe why an attachment matched the context."""
|
||||
from litellm.proxy.policy_engine.policy_matcher import PolicyMatcher
|
||||
|
||||
if attachment.is_global():
|
||||
return "scope:*"
|
||||
|
||||
reasons = []
|
||||
if attachment.tags and context.tags:
|
||||
matching_tags = [
|
||||
t for t in context.tags
|
||||
if PolicyMatcher.matches_pattern(t, attachment.tags)
|
||||
]
|
||||
if matching_tags:
|
||||
reasons.append(f"tag:{matching_tags[0]}")
|
||||
if attachment.teams and context.team_alias:
|
||||
reasons.append(f"team:{context.team_alias}")
|
||||
if attachment.keys and context.key_alias:
|
||||
reasons.append(f"key:{context.key_alias}")
|
||||
if attachment.models and context.model:
|
||||
reasons.append(f"model:{context.model}")
|
||||
|
||||
return "+".join(reasons) if reasons else "scope:default"
|
||||
|
||||
def is_policy_attached(
|
||||
self, policy_name: str, context: PolicyMatchContext
|
||||
|
|
@ -238,6 +286,7 @@ class AttachmentRegistry:
|
|||
"teams": attachment_request.teams or [],
|
||||
"keys": attachment_request.keys or [],
|
||||
"models": attachment_request.models or [],
|
||||
"tags": attachment_request.tags or [],
|
||||
"created_at": datetime.now(timezone.utc),
|
||||
"updated_at": datetime.now(timezone.utc),
|
||||
"created_by": created_by,
|
||||
|
|
@ -253,6 +302,7 @@ class AttachmentRegistry:
|
|||
teams=attachment_request.teams,
|
||||
keys=attachment_request.keys,
|
||||
models=attachment_request.models,
|
||||
tags=attachment_request.tags,
|
||||
)
|
||||
self.add_attachment(attachment)
|
||||
|
||||
|
|
@ -263,6 +313,7 @@ class AttachmentRegistry:
|
|||
teams=created_attachment.teams or [],
|
||||
keys=created_attachment.keys or [],
|
||||
models=created_attachment.models or [],
|
||||
tags=created_attachment.tags or [],
|
||||
created_at=created_attachment.created_at,
|
||||
updated_at=created_attachment.updated_at,
|
||||
created_by=created_attachment.created_by,
|
||||
|
|
@ -344,6 +395,7 @@ class AttachmentRegistry:
|
|||
teams=attachment.teams or [],
|
||||
keys=attachment.keys or [],
|
||||
models=attachment.models or [],
|
||||
tags=attachment.tags or [],
|
||||
created_at=attachment.created_at,
|
||||
updated_at=attachment.updated_at,
|
||||
created_by=attachment.created_by,
|
||||
|
|
@ -381,6 +433,7 @@ class AttachmentRegistry:
|
|||
teams=a.teams or [],
|
||||
keys=a.keys or [],
|
||||
models=a.models or [],
|
||||
tags=a.tags or [],
|
||||
created_at=a.created_at,
|
||||
updated_at=a.updated_at,
|
||||
created_by=a.created_by,
|
||||
|
|
@ -415,6 +468,7 @@ class AttachmentRegistry:
|
|||
teams=attachment_response.teams if attachment_response.teams else None,
|
||||
keys=attachment_response.keys if attachment_response.keys else None,
|
||||
models=attachment_response.models if attachment_response.models else None,
|
||||
tags=attachment_response.tags if attachment_response.tags else None,
|
||||
)
|
||||
self._attachments.append(attachment)
|
||||
|
||||
|
|
|
|||
|
|
@ -23,10 +23,6 @@ from litellm.types.proxy.policy_engine import (
|
|||
|
||||
router = APIRouter()
|
||||
|
||||
# Get singleton instances
|
||||
POLICY_REGISTRY = get_policy_registry()
|
||||
ATTACHMENT_REGISTRY = get_attachment_registry()
|
||||
|
||||
|
||||
# ─────────────────────────────────────────────────────────────────────────────
|
||||
# Policy CRUD Endpoints
|
||||
|
|
@ -75,7 +71,7 @@ async def list_policies():
|
|||
raise HTTPException(status_code=500, detail="Database not connected")
|
||||
|
||||
try:
|
||||
policies = await POLICY_REGISTRY.get_all_policies_from_db(prisma_client)
|
||||
policies = await get_policy_registry().get_all_policies_from_db(prisma_client)
|
||||
return PolicyListDBResponse(policies=policies, total_count=len(policies))
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.exception(f"Error listing policies: {e}")
|
||||
|
|
@ -130,7 +126,7 @@ async def create_policy(
|
|||
|
||||
try:
|
||||
created_by = user_api_key_dict.user_id
|
||||
result = await POLICY_REGISTRY.add_policy_to_db(
|
||||
result = await get_policy_registry().add_policy_to_db(
|
||||
policy_request=request,
|
||||
prisma_client=prisma_client,
|
||||
created_by=created_by,
|
||||
|
|
@ -168,7 +164,7 @@ async def get_policy(policy_id: str):
|
|||
raise HTTPException(status_code=500, detail="Database not connected")
|
||||
|
||||
try:
|
||||
result = await POLICY_REGISTRY.get_policy_by_id_from_db(
|
||||
result = await get_policy_registry().get_policy_by_id_from_db(
|
||||
policy_id=policy_id,
|
||||
prisma_client=prisma_client,
|
||||
)
|
||||
|
|
@ -216,7 +212,7 @@ async def update_policy(
|
|||
|
||||
try:
|
||||
# Check if policy exists
|
||||
existing = await POLICY_REGISTRY.get_policy_by_id_from_db(
|
||||
existing = await get_policy_registry().get_policy_by_id_from_db(
|
||||
policy_id=policy_id,
|
||||
prisma_client=prisma_client,
|
||||
)
|
||||
|
|
@ -226,7 +222,7 @@ async def update_policy(
|
|||
)
|
||||
|
||||
updated_by = user_api_key_dict.user_id
|
||||
result = await POLICY_REGISTRY.update_policy_in_db(
|
||||
result = await get_policy_registry().update_policy_in_db(
|
||||
policy_id=policy_id,
|
||||
policy_request=request,
|
||||
prisma_client=prisma_client,
|
||||
|
|
@ -269,7 +265,7 @@ async def delete_policy(policy_id: str):
|
|||
|
||||
try:
|
||||
# Check if policy exists
|
||||
existing = await POLICY_REGISTRY.get_policy_by_id_from_db(
|
||||
existing = await get_policy_registry().get_policy_by_id_from_db(
|
||||
policy_id=policy_id,
|
||||
prisma_client=prisma_client,
|
||||
)
|
||||
|
|
@ -278,7 +274,7 @@ async def delete_policy(policy_id: str):
|
|||
status_code=404, detail=f"Policy with ID {policy_id} not found"
|
||||
)
|
||||
|
||||
result = await POLICY_REGISTRY.delete_policy_from_db(
|
||||
result = await get_policy_registry().delete_policy_from_db(
|
||||
policy_id=policy_id,
|
||||
prisma_client=prisma_client,
|
||||
)
|
||||
|
|
@ -324,7 +320,7 @@ async def get_resolved_guardrails(policy_id: str):
|
|||
|
||||
try:
|
||||
# Get the policy
|
||||
policy = await POLICY_REGISTRY.get_policy_by_id_from_db(
|
||||
policy = await get_policy_registry().get_policy_by_id_from_db(
|
||||
policy_id=policy_id,
|
||||
prisma_client=prisma_client,
|
||||
)
|
||||
|
|
@ -334,7 +330,7 @@ async def get_resolved_guardrails(policy_id: str):
|
|||
)
|
||||
|
||||
# Resolve guardrails
|
||||
resolved = await POLICY_REGISTRY.resolve_guardrails_from_db(
|
||||
resolved = await get_policy_registry().resolve_guardrails_from_db(
|
||||
policy_name=policy.policy_name,
|
||||
prisma_client=prisma_client,
|
||||
)
|
||||
|
|
@ -399,7 +395,7 @@ async def list_policy_attachments():
|
|||
raise HTTPException(status_code=500, detail="Database not connected")
|
||||
|
||||
try:
|
||||
attachments = await ATTACHMENT_REGISTRY.get_all_attachments_from_db(
|
||||
attachments = await get_attachment_registry().get_all_attachments_from_db(
|
||||
prisma_client
|
||||
)
|
||||
return PolicyAttachmentListResponse(
|
||||
|
|
@ -466,7 +462,7 @@ async def create_policy_attachment(
|
|||
|
||||
try:
|
||||
# Verify the policy exists
|
||||
policy = await POLICY_REGISTRY.get_all_policies_from_db(prisma_client)
|
||||
policy = await get_policy_registry().get_all_policies_from_db(prisma_client)
|
||||
policy_names = [p.policy_name for p in policy]
|
||||
if request.policy_name not in policy_names:
|
||||
raise HTTPException(
|
||||
|
|
@ -475,7 +471,7 @@ async def create_policy_attachment(
|
|||
)
|
||||
|
||||
created_by = user_api_key_dict.user_id
|
||||
result = await ATTACHMENT_REGISTRY.add_attachment_to_db(
|
||||
result = await get_attachment_registry().add_attachment_to_db(
|
||||
attachment_request=request,
|
||||
prisma_client=prisma_client,
|
||||
created_by=created_by,
|
||||
|
|
@ -510,7 +506,7 @@ async def get_policy_attachment(attachment_id: str):
|
|||
raise HTTPException(status_code=500, detail="Database not connected")
|
||||
|
||||
try:
|
||||
result = await ATTACHMENT_REGISTRY.get_attachment_by_id_from_db(
|
||||
result = await get_attachment_registry().get_attachment_by_id_from_db(
|
||||
attachment_id=attachment_id,
|
||||
prisma_client=prisma_client,
|
||||
)
|
||||
|
|
@ -556,7 +552,7 @@ async def delete_policy_attachment(attachment_id: str):
|
|||
|
||||
try:
|
||||
# Check if attachment exists
|
||||
existing = await ATTACHMENT_REGISTRY.get_attachment_by_id_from_db(
|
||||
existing = await get_attachment_registry().get_attachment_by_id_from_db(
|
||||
attachment_id=attachment_id,
|
||||
prisma_client=prisma_client,
|
||||
)
|
||||
|
|
@ -566,7 +562,7 @@ async def delete_policy_attachment(attachment_id: str):
|
|||
detail=f"Attachment with ID {attachment_id} not found",
|
||||
)
|
||||
|
||||
result = await ATTACHMENT_REGISTRY.delete_attachment_from_db(
|
||||
result = await get_attachment_registry().delete_attachment_from_db(
|
||||
attachment_id=attachment_id,
|
||||
prisma_client=prisma_client,
|
||||
)
|
||||
|
|
|
|||
|
|
@ -81,6 +81,19 @@ class PolicyMatcher:
|
|||
if not PolicyMatcher.matches_pattern(context.model, scope.get_models()):
|
||||
return False
|
||||
|
||||
# Check tags (only if scope specifies tags)
|
||||
# Unlike teams/keys/models, empty tags means "do not check" rather than "match all"
|
||||
scope_tags = scope.get_tags()
|
||||
if scope_tags:
|
||||
if not context.tags:
|
||||
return False
|
||||
# Match if ANY context tag matches ANY scope tag pattern
|
||||
if not any(
|
||||
PolicyMatcher.matches_pattern(tag, scope_tags)
|
||||
for tag in context.tags
|
||||
):
|
||||
return False
|
||||
|
||||
return True
|
||||
|
||||
@staticmethod
|
||||
|
|
|
|||
|
|
@ -484,6 +484,7 @@ class PolicyRegistry:
|
|||
)
|
||||
self.add_policy(policy_response.policy_name, policy)
|
||||
|
||||
self._initialized = True
|
||||
verbose_proxy_logger.info(
|
||||
f"Synced {len(policies)} policies from DB to in-memory registry"
|
||||
)
|
||||
|
|
|
|||
408
litellm/proxy/policy_engine/policy_resolve_endpoints.py
Normal file
408
litellm/proxy/policy_engine/policy_resolve_endpoints.py
Normal file
|
|
@ -0,0 +1,408 @@
|
|||
"""
|
||||
Policy resolve and attachment impact estimation endpoints.
|
||||
|
||||
- /policies/resolve — debug which guardrails apply for a given context
|
||||
- /policies/attachments/estimate-impact — preview blast radius before creating an attachment
|
||||
"""
|
||||
|
||||
import json
|
||||
|
||||
from fastapi import APIRouter, Depends, HTTPException, Query
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.constants import MAX_POLICY_ESTIMATE_IMPACT_ROWS
|
||||
from litellm.proxy._types import UserAPIKeyAuth
|
||||
from litellm.proxy.auth.user_api_key_auth import user_api_key_auth
|
||||
from litellm.proxy.policy_engine.attachment_registry import get_attachment_registry
|
||||
from litellm.proxy.policy_engine.policy_registry import get_policy_registry
|
||||
from litellm.types.proxy.policy_engine import (
|
||||
AttachmentImpactResponse,
|
||||
PolicyAttachmentCreateRequest,
|
||||
PolicyMatchContext,
|
||||
PolicyMatchDetail,
|
||||
PolicyResolveRequest,
|
||||
PolicyResolveResponse,
|
||||
)
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
|
||||
def _build_alias_where(field: str, patterns: list) -> dict:
|
||||
"""Build a Prisma ``where`` clause for alias patterns.
|
||||
|
||||
Supports exact matches and suffix wildcards (``prefix*``).
|
||||
Returns something like:
|
||||
{"OR": [{"field": {"in": ["a","b"]}}, {"field": {"startsWith": "dev-"}}]}
|
||||
"""
|
||||
exact: list = []
|
||||
prefix_conditions: list = []
|
||||
for pat in patterns:
|
||||
if pat.endswith("*"):
|
||||
prefix_conditions.append({field: {"startsWith": pat[:-1]}})
|
||||
else:
|
||||
exact.append(pat)
|
||||
|
||||
conditions: list = []
|
||||
if exact:
|
||||
conditions.append({field: {"in": exact}})
|
||||
conditions.extend(prefix_conditions)
|
||||
|
||||
if not conditions:
|
||||
return {field: {"not": None}}
|
||||
if len(conditions) == 1:
|
||||
return conditions[0]
|
||||
return {"OR": conditions}
|
||||
|
||||
|
||||
def _parse_metadata(raw_metadata: object) -> dict:
|
||||
"""Parse metadata that may be a dict, JSON string, or None."""
|
||||
if raw_metadata is None:
|
||||
return {}
|
||||
if isinstance(raw_metadata, str):
|
||||
try:
|
||||
return json.loads(raw_metadata)
|
||||
except (json.JSONDecodeError, TypeError):
|
||||
return {}
|
||||
return raw_metadata if isinstance(raw_metadata, dict) else {}
|
||||
|
||||
|
||||
def _get_tags_from_metadata(metadata: object, json_metadata: object = None) -> list:
|
||||
"""Extract tags list from a metadata field (or metadata_json fallback)."""
|
||||
raw = json_metadata if json_metadata is not None else metadata
|
||||
parsed = _parse_metadata(raw)
|
||||
return parsed.get("tags", []) or []
|
||||
|
||||
|
||||
async def _fetch_all_teams(prisma_client: object) -> list:
|
||||
"""Fetch teams from DB once. Reuse the result across tag and alias lookups."""
|
||||
return await prisma_client.db.litellm_teamtable.find_many( # type: ignore
|
||||
where={}, order={"created_at": "desc"}, take=MAX_POLICY_ESTIMATE_IMPACT_ROWS,
|
||||
)
|
||||
|
||||
|
||||
def _filter_keys_by_tags(keys: list, tag_patterns: list) -> tuple:
|
||||
"""Filter key rows whose metadata.tags match any of the given patterns.
|
||||
|
||||
Returns (named_aliases, unnamed_count).
|
||||
"""
|
||||
from litellm.proxy.auth.route_checks import RouteChecks
|
||||
|
||||
affected: list = []
|
||||
unnamed_count = 0
|
||||
for key in keys:
|
||||
key_alias = key.key_alias or ""
|
||||
key_tags = _get_tags_from_metadata(
|
||||
key.metadata, getattr(key, "metadata_json", None)
|
||||
)
|
||||
if key_tags and any(
|
||||
RouteChecks._route_matches_wildcard_pattern(route=tag, pattern=pat)
|
||||
for tag in key_tags
|
||||
for pat in tag_patterns
|
||||
):
|
||||
if key_alias:
|
||||
affected.append(key_alias)
|
||||
else:
|
||||
unnamed_count += 1
|
||||
return affected, unnamed_count
|
||||
|
||||
|
||||
def _filter_teams_by_tags(teams: list, tag_patterns: list) -> tuple:
|
||||
"""Filter pre-fetched team rows whose metadata.tags match any patterns.
|
||||
|
||||
Returns (named_aliases, unnamed_count).
|
||||
"""
|
||||
from litellm.proxy.auth.route_checks import RouteChecks
|
||||
|
||||
affected: list = []
|
||||
unnamed_count = 0
|
||||
for team in teams:
|
||||
team_alias = team.team_alias or ""
|
||||
team_tags = _get_tags_from_metadata(team.metadata)
|
||||
if team_tags and any(
|
||||
RouteChecks._route_matches_wildcard_pattern(route=tag, pattern=pat)
|
||||
for tag in team_tags
|
||||
for pat in tag_patterns
|
||||
):
|
||||
if team_alias:
|
||||
affected.append(team_alias)
|
||||
else:
|
||||
unnamed_count += 1
|
||||
return affected, unnamed_count
|
||||
|
||||
|
||||
async def _find_affected_by_team_patterns(
|
||||
prisma_client: object,
|
||||
all_teams: list,
|
||||
team_patterns: list,
|
||||
existing_teams: list,
|
||||
existing_keys: list,
|
||||
) -> tuple:
|
||||
"""Filter pre-fetched teams by alias patterns, then fetch their keys.
|
||||
|
||||
Returns (new_teams, new_keys, unnamed_keys_count).
|
||||
"""
|
||||
from litellm.proxy.auth.route_checks import RouteChecks
|
||||
|
||||
new_teams: list = []
|
||||
matched_team_ids: list = []
|
||||
|
||||
for team in all_teams:
|
||||
team_alias = team.team_alias or ""
|
||||
if team_alias and any(
|
||||
RouteChecks._route_matches_wildcard_pattern(route=team_alias, pattern=pat)
|
||||
for pat in team_patterns
|
||||
):
|
||||
if team_alias not in existing_teams:
|
||||
new_teams.append(team_alias)
|
||||
matched_team_ids.append(str(team.team_id))
|
||||
|
||||
new_keys: list = []
|
||||
unnamed_keys_count = 0
|
||||
if matched_team_ids:
|
||||
keys = await prisma_client.db.litellm_verificationtoken.find_many( # type: ignore
|
||||
where={"team_id": {"in": matched_team_ids}},
|
||||
order={"created_at": "desc"}, take=MAX_POLICY_ESTIMATE_IMPACT_ROWS,
|
||||
)
|
||||
for key in keys:
|
||||
key_alias = key.key_alias or ""
|
||||
if key_alias:
|
||||
if key_alias not in existing_keys:
|
||||
new_keys.append(key_alias)
|
||||
else:
|
||||
unnamed_keys_count += 1
|
||||
|
||||
return new_teams, new_keys, unnamed_keys_count
|
||||
|
||||
|
||||
async def _find_affected_keys_by_alias(
|
||||
prisma_client: object, key_patterns: list, existing_keys: list
|
||||
) -> list:
|
||||
"""Find keys whose alias matches the given patterns."""
|
||||
from litellm.proxy.auth.route_checks import RouteChecks
|
||||
|
||||
affected: list = []
|
||||
|
||||
keys = await prisma_client.db.litellm_verificationtoken.find_many( # type: ignore
|
||||
where=_build_alias_where("key_alias", key_patterns),
|
||||
order={"created_at": "desc"}, take=MAX_POLICY_ESTIMATE_IMPACT_ROWS,
|
||||
)
|
||||
for key in keys:
|
||||
key_alias = key.key_alias or ""
|
||||
if key_alias and any(
|
||||
RouteChecks._route_matches_wildcard_pattern(route=key_alias, pattern=pat)
|
||||
for pat in key_patterns
|
||||
):
|
||||
if key_alias not in existing_keys:
|
||||
affected.append(key_alias)
|
||||
return affected
|
||||
|
||||
|
||||
# ─────────────────────────────────────────────────────────────────────────────
|
||||
# Policy Resolve Endpoint
|
||||
# ─────────────────────────────────────────────────────────────────────────────
|
||||
|
||||
|
||||
@router.post(
|
||||
"/policies/resolve",
|
||||
tags=["Policies"],
|
||||
dependencies=[Depends(user_api_key_auth)],
|
||||
response_model=PolicyResolveResponse,
|
||||
)
|
||||
async def resolve_policies_for_context(
|
||||
request: PolicyResolveRequest,
|
||||
force_sync: bool = Query(
|
||||
default=False,
|
||||
description="Force a DB sync before resolving. Default uses in-memory cache.",
|
||||
),
|
||||
user_api_key_dict: UserAPIKeyAuth = Depends(user_api_key_auth),
|
||||
):
|
||||
"""
|
||||
Resolve which policies and guardrails apply for a given context.
|
||||
|
||||
Use this endpoint to debug "what guardrails would apply to a request
|
||||
with this team/key/model/tags combination?"
|
||||
|
||||
Example Request:
|
||||
```bash
|
||||
curl -X POST "http://localhost:4000/policies/resolve" \\
|
||||
-H "Authorization: Bearer <your_api_key>" \\
|
||||
-H "Content-Type: application/json" \\
|
||||
-d '{
|
||||
"tags": ["healthcare"],
|
||||
"model": "gpt-4"
|
||||
}'
|
||||
```
|
||||
"""
|
||||
from litellm.proxy.policy_engine.policy_matcher import PolicyMatcher
|
||||
from litellm.proxy.policy_engine.policy_resolver import PolicyResolver
|
||||
from litellm.proxy.proxy_server import prisma_client
|
||||
|
||||
if prisma_client is None:
|
||||
raise HTTPException(status_code=500, detail="Database not connected")
|
||||
|
||||
try:
|
||||
# Only sync from DB when explicitly requested; otherwise use in-memory cache
|
||||
if force_sync:
|
||||
await get_policy_registry().sync_policies_from_db(prisma_client)
|
||||
await get_attachment_registry().sync_attachments_from_db(prisma_client)
|
||||
|
||||
# Build context from request
|
||||
context = PolicyMatchContext(
|
||||
team_alias=request.team_alias,
|
||||
key_alias=request.key_alias,
|
||||
model=request.model,
|
||||
tags=request.tags,
|
||||
)
|
||||
|
||||
# Get matching policies with reasons
|
||||
match_results = get_attachment_registry().get_attached_policies_with_reasons(
|
||||
context=context
|
||||
)
|
||||
|
||||
if not match_results:
|
||||
return PolicyResolveResponse(
|
||||
effective_guardrails=[],
|
||||
matched_policies=[],
|
||||
)
|
||||
|
||||
# Filter by conditions
|
||||
policy_names = [r["policy_name"] for r in match_results]
|
||||
applied_policy_names = PolicyMatcher.get_policies_with_matching_conditions(
|
||||
policy_names=policy_names,
|
||||
context=context,
|
||||
)
|
||||
|
||||
# Resolve guardrails for each applied policy
|
||||
matched_policies = []
|
||||
all_guardrails: set = set()
|
||||
for result in match_results:
|
||||
pname = result["policy_name"]
|
||||
if pname not in applied_policy_names:
|
||||
continue
|
||||
resolved = PolicyResolver.resolve_policy_guardrails(
|
||||
policy_name=pname,
|
||||
policies=get_policy_registry().get_all_policies(),
|
||||
context=context,
|
||||
)
|
||||
guardrails = resolved.guardrails if resolved else []
|
||||
all_guardrails.update(guardrails)
|
||||
matched_policies.append(
|
||||
PolicyMatchDetail(
|
||||
policy_name=pname,
|
||||
matched_via=result["matched_via"],
|
||||
guardrails_added=guardrails,
|
||||
)
|
||||
)
|
||||
|
||||
return PolicyResolveResponse(
|
||||
effective_guardrails=sorted(all_guardrails),
|
||||
matched_policies=matched_policies,
|
||||
)
|
||||
except HTTPException:
|
||||
raise
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.exception(f"Error resolving policies: {e}")
|
||||
raise HTTPException(status_code=500, detail=str(e))
|
||||
|
||||
|
||||
# ─────────────────────────────────────────────────────────────────────────────
|
||||
# Attachment Impact Estimation Endpoint
|
||||
# ─────────────────────────────────────────────────────────────────────────────
|
||||
|
||||
|
||||
@router.post(
|
||||
"/policies/attachments/estimate-impact",
|
||||
tags=["Policies"],
|
||||
dependencies=[Depends(user_api_key_auth)],
|
||||
response_model=AttachmentImpactResponse,
|
||||
)
|
||||
async def estimate_attachment_impact(
|
||||
request: PolicyAttachmentCreateRequest,
|
||||
user_api_key_dict: UserAPIKeyAuth = Depends(user_api_key_auth),
|
||||
):
|
||||
"""
|
||||
Estimate how many keys and teams would be affected by a policy attachment.
|
||||
|
||||
Use this before creating an attachment to preview the blast radius.
|
||||
|
||||
Example Request:
|
||||
```bash
|
||||
curl -X POST "http://localhost:4000/policies/attachments/estimate-impact" \\
|
||||
-H "Authorization: Bearer <your_api_key>" \\
|
||||
-H "Content-Type: application/json" \\
|
||||
-d '{
|
||||
"policy_name": "hipaa-compliance",
|
||||
"tags": ["healthcare", "health-*"]
|
||||
}'
|
||||
```
|
||||
"""
|
||||
from litellm.proxy.proxy_server import prisma_client
|
||||
|
||||
if prisma_client is None:
|
||||
raise HTTPException(status_code=500, detail="Database not connected")
|
||||
|
||||
try:
|
||||
# If global scope, everything is affected — not useful to enumerate
|
||||
if request.scope == "*":
|
||||
return AttachmentImpactResponse(
|
||||
affected_keys_count=-1,
|
||||
affected_teams_count=-1,
|
||||
sample_keys=["(global scope — affects all keys)"],
|
||||
sample_teams=["(global scope — affects all teams)"],
|
||||
)
|
||||
|
||||
affected_keys: list = []
|
||||
affected_teams: list = []
|
||||
unnamed_keys = 0
|
||||
unnamed_teams = 0
|
||||
|
||||
tag_patterns = request.tags or []
|
||||
team_patterns = request.teams or []
|
||||
|
||||
# Fetch teams once — reused by both tag-based and alias-based lookups
|
||||
all_teams: list = []
|
||||
if tag_patterns or team_patterns:
|
||||
all_teams = await _fetch_all_teams(prisma_client)
|
||||
|
||||
# Tag-based impact
|
||||
if tag_patterns:
|
||||
keys = await prisma_client.db.litellm_verificationtoken.find_many( # type: ignore
|
||||
where={}, order={"created_at": "desc"},
|
||||
take=MAX_POLICY_ESTIMATE_IMPACT_ROWS,
|
||||
)
|
||||
affected_keys, unnamed_keys = _filter_keys_by_tags(keys, tag_patterns)
|
||||
affected_teams, unnamed_teams = _filter_teams_by_tags(
|
||||
all_teams, tag_patterns,
|
||||
)
|
||||
|
||||
# Team-based impact (alias matching + keys belonging to those teams)
|
||||
if team_patterns:
|
||||
new_teams, new_keys, new_unnamed = await _find_affected_by_team_patterns(
|
||||
prisma_client, all_teams, team_patterns,
|
||||
affected_teams, affected_keys,
|
||||
)
|
||||
affected_teams.extend(new_teams)
|
||||
affected_keys.extend(new_keys)
|
||||
unnamed_keys += new_unnamed
|
||||
|
||||
# Key-based impact (direct alias matching)
|
||||
key_patterns = request.keys or []
|
||||
if key_patterns:
|
||||
new_keys = await _find_affected_keys_by_alias(
|
||||
prisma_client, key_patterns, affected_keys,
|
||||
)
|
||||
affected_keys.extend(new_keys)
|
||||
|
||||
return AttachmentImpactResponse(
|
||||
affected_keys_count=len(affected_keys) + unnamed_keys,
|
||||
affected_teams_count=len(affected_teams) + unnamed_teams,
|
||||
unnamed_keys_count=unnamed_keys,
|
||||
unnamed_teams_count=unnamed_teams,
|
||||
sample_keys=affected_keys[:10],
|
||||
sample_teams=affected_teams[:10],
|
||||
)
|
||||
except HTTPException:
|
||||
raise
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.exception(f"Error estimating attachment impact: {e}")
|
||||
raise HTTPException(status_code=500, detail=str(e))
|
||||
|
|
@ -338,7 +338,10 @@ from litellm.proxy.management_endpoints.cache_settings_endpoints import (
|
|||
from litellm.proxy.management_endpoints.callback_management_endpoints import (
|
||||
router as callback_management_endpoints_router,
|
||||
)
|
||||
from litellm.proxy.management_endpoints.common_utils import _user_has_admin_view
|
||||
from litellm.proxy.management_endpoints.common_utils import (
|
||||
admin_can_invite_user,
|
||||
_user_has_admin_privileges,
|
||||
)
|
||||
from litellm.proxy.management_endpoints.cost_tracking_settings import (
|
||||
router as cost_tracking_settings_router,
|
||||
)
|
||||
|
|
@ -427,6 +430,9 @@ from litellm.proxy.pass_through_endpoints.pass_through_endpoints import (
|
|||
router as pass_through_router,
|
||||
)
|
||||
from litellm.proxy.policy_engine.policy_endpoints import router as policy_crud_router
|
||||
from litellm.proxy.policy_engine.policy_resolve_endpoints import (
|
||||
router as policy_resolve_router,
|
||||
)
|
||||
from litellm.proxy.prompts.prompt_endpoints import router as prompts_router
|
||||
from litellm.proxy.public_endpoints import router as public_endpoints_router
|
||||
from litellm.proxy.rag_endpoints.endpoints import router as rag_router
|
||||
|
|
@ -4603,11 +4609,16 @@ async def initialize( # noqa: PLR0915
|
|||
elif litellm_log_setting.upper() == "DEBUG":
|
||||
import logging
|
||||
|
||||
from litellm._logging import verbose_proxy_logger, verbose_router_logger
|
||||
from litellm._logging import (
|
||||
verbose_logger,
|
||||
verbose_proxy_logger,
|
||||
verbose_router_logger,
|
||||
)
|
||||
|
||||
verbose_logger.setLevel(level=logging.DEBUG) # set package log to debug
|
||||
verbose_router_logger.setLevel(
|
||||
level=logging.DEBUG
|
||||
) # set router logs to info
|
||||
) # set router logs to debug
|
||||
verbose_proxy_logger.setLevel(
|
||||
level=logging.DEBUG
|
||||
) # set proxy logs to debug
|
||||
|
|
@ -10372,7 +10383,17 @@ async def new_invitation(
|
|||
detail={"error": CommonProxyErrors.db_not_connected_error.value},
|
||||
)
|
||||
|
||||
if user_api_key_dict.user_role != LitellmUserRoles.PROXY_ADMIN:
|
||||
# Allow proxy admins and org/team admins (admin status from DB via get_user_object)
|
||||
has_access = (
|
||||
user_api_key_dict.user_role == LitellmUserRoles.PROXY_ADMIN
|
||||
or await _user_has_admin_privileges(
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
proxy_logging_obj=proxy_logging_obj,
|
||||
)
|
||||
)
|
||||
if not has_access:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail={
|
||||
|
|
@ -10383,6 +10404,23 @@ async def new_invitation(
|
|||
},
|
||||
)
|
||||
|
||||
# Org/team admins can only invite users within their org/team
|
||||
if user_api_key_dict.user_role != LitellmUserRoles.PROXY_ADMIN:
|
||||
can_invite = await admin_can_invite_user(
|
||||
target_user_id=data.user_id,
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
proxy_logging_obj=proxy_logging_obj,
|
||||
)
|
||||
if not can_invite:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail={
|
||||
"error": "You can only create invitations for users in your organization or team."
|
||||
},
|
||||
)
|
||||
|
||||
response = await create_invitation_for_user(
|
||||
data=data,
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
|
|
@ -10535,7 +10573,16 @@ async def invitation_delete(
|
|||
detail={"error": CommonProxyErrors.db_not_connected_error.value},
|
||||
)
|
||||
|
||||
if user_api_key_dict.user_role != LitellmUserRoles.PROXY_ADMIN:
|
||||
# Proxy admins can delete any invitation; org admins only their own
|
||||
is_proxy_admin = user_api_key_dict.user_role == LitellmUserRoles.PROXY_ADMIN
|
||||
is_other_admin = await _user_has_admin_privileges(
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
proxy_logging_obj=proxy_logging_obj,
|
||||
)
|
||||
|
||||
if not is_proxy_admin and not is_other_admin:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail={
|
||||
|
|
@ -10546,6 +10593,24 @@ async def invitation_delete(
|
|||
},
|
||||
)
|
||||
|
||||
# Org admins can only delete invitations they created
|
||||
if is_other_admin and not is_proxy_admin:
|
||||
invitation = await prisma_client.db.litellm_invitationlink.find_unique(
|
||||
where={"id": data.invitation_id}
|
||||
)
|
||||
if invitation is None:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail={"error": "Invitation id does not exist in the database."},
|
||||
)
|
||||
if invitation.created_by != user_api_key_dict.user_id:
|
||||
raise HTTPException(
|
||||
status_code=403,
|
||||
detail={
|
||||
"error": "Organization admins can only delete invitations they created."
|
||||
},
|
||||
)
|
||||
|
||||
response = await prisma_client.db.litellm_invitationlink.delete(
|
||||
where={"id": data.invitation_id}
|
||||
)
|
||||
|
|
@ -11746,6 +11811,7 @@ app.include_router(analytics_router)
|
|||
app.include_router(guardrails_router)
|
||||
app.include_router(policy_router)
|
||||
app.include_router(policy_crud_router)
|
||||
app.include_router(policy_resolve_router)
|
||||
app.include_router(search_tool_management_router)
|
||||
app.include_router(prompts_router)
|
||||
app.include_router(callback_management_endpoints_router)
|
||||
|
|
|
|||
|
|
@ -911,6 +911,7 @@ model LiteLLM_PolicyAttachmentTable {
|
|||
teams String[] @default([]) // Team aliases or patterns
|
||||
keys String[] @default([]) // Key aliases or patterns
|
||||
models String[] @default([]) // Model names or patterns
|
||||
tags String[] @default([]) // Tag patterns (e.g., ["healthcare", "prod-*"])
|
||||
created_at DateTime @default(now())
|
||||
created_by String?
|
||||
updated_at DateTime @default(now()) @updatedAt
|
||||
|
|
|
|||
|
|
@ -1686,6 +1686,14 @@ async def ui_view_spend_logs( # noqa: PLR0915
|
|||
error_message: Optional[str] = fastapi.Query(
|
||||
default=None, description="Filter logs by error message (partial string match)"
|
||||
),
|
||||
sort_by: str = fastapi.Query(
|
||||
default="startTime",
|
||||
description="Sort logs by field: spend, total_tokens, startTime, or endTime",
|
||||
),
|
||||
sort_order: Optional[str] = fastapi.Query(
|
||||
default="desc",
|
||||
description="Sort order: asc or desc",
|
||||
),
|
||||
):
|
||||
"""
|
||||
View spend logs with pagination support.
|
||||
|
|
@ -1717,6 +1725,23 @@ async def ui_view_spend_logs( # noqa: PLR0915
|
|||
code=status.HTTP_400_BAD_REQUEST,
|
||||
)
|
||||
|
||||
# Validate sort_by and sort_order
|
||||
valid_sort_fields = {"spend", "total_tokens", "startTime", "endTime"}
|
||||
if sort_by not in valid_sort_fields:
|
||||
raise ProxyException(
|
||||
message=f"Invalid sort_by: {sort_by}. Must be one of: {', '.join(sorted(valid_sort_fields))}",
|
||||
type="bad_request",
|
||||
param="sort_by",
|
||||
code=status.HTTP_400_BAD_REQUEST,
|
||||
)
|
||||
if sort_order is not None and sort_order.lower() not in {"asc", "desc"}:
|
||||
raise ProxyException(
|
||||
message=f"Invalid sort_order: {sort_order}. Must be one of: asc, desc",
|
||||
type="bad_request",
|
||||
param="sort_order",
|
||||
code=status.HTTP_400_BAD_REQUEST,
|
||||
)
|
||||
|
||||
try:
|
||||
is_v2 = "/spend/logs/v2" in request.url.path
|
||||
formats = ["%Y-%m-%d %H:%M:%S", "%Y-%m-%d"] if is_v2 else ["%Y-%m-%d %H:%M:%S"]
|
||||
|
|
@ -1829,6 +1854,11 @@ async def ui_view_spend_logs( # noqa: PLR0915
|
|||
# Calculate skip value for pagination
|
||||
skip = (page - 1) * page_size
|
||||
|
||||
# Build order clause from sort_by and sort_order
|
||||
order_column = sort_by
|
||||
order_direction = (sort_order or "desc").lower()
|
||||
order_clause = {order_column: order_direction}
|
||||
|
||||
# Get total count of records
|
||||
total_records = await prisma_client.db.litellm_spendlogs.count(
|
||||
where=where_conditions,
|
||||
|
|
|
|||
|
|
@ -58,7 +58,6 @@ from litellm.litellm_core_utils.core_helpers import (
|
|||
_get_parent_otel_span_from_kwargs,
|
||||
get_metadata_variable_name_from_kwargs,
|
||||
)
|
||||
from litellm.litellm_core_utils.thread_pool_executor import executor
|
||||
from litellm.litellm_core_utils.coroutine_checker import coroutine_checker
|
||||
from litellm.litellm_core_utils.credential_accessor import CredentialAccessor
|
||||
from litellm.litellm_core_utils.dd_tracing import tracer
|
||||
|
|
@ -619,11 +618,12 @@ class Router:
|
|||
self.retry_policy = RetryPolicy(**retry_policy)
|
||||
elif isinstance(retry_policy, RetryPolicy):
|
||||
self.retry_policy = retry_policy
|
||||
verbose_router_logger.info(
|
||||
"\033[32mRouter Custom Retry Policy Set:\n{}\033[0m".format(
|
||||
self.retry_policy.model_dump(exclude_none=True)
|
||||
if self.retry_policy is not None:
|
||||
verbose_router_logger.info(
|
||||
"\033[32mRouter Custom Retry Policy Set:\n{}\033[0m".format(
|
||||
self.retry_policy.model_dump(exclude_none=True)
|
||||
)
|
||||
)
|
||||
)
|
||||
|
||||
self.model_group_retry_policy: Optional[
|
||||
Dict[str, RetryPolicy]
|
||||
|
|
@ -636,11 +636,12 @@ class Router:
|
|||
elif isinstance(allowed_fails_policy, AllowedFailsPolicy):
|
||||
self.allowed_fails_policy = allowed_fails_policy
|
||||
|
||||
verbose_router_logger.info(
|
||||
"\033[32mRouter Custom Allowed Fails Policy Set:\n{}\033[0m".format(
|
||||
self.allowed_fails_policy.model_dump(exclude_none=True)
|
||||
if self.allowed_fails_policy is not None:
|
||||
verbose_router_logger.info(
|
||||
"\033[32mRouter Custom Allowed Fails Policy Set:\n{}\033[0m".format(
|
||||
self.allowed_fails_policy.model_dump(exclude_none=True)
|
||||
)
|
||||
)
|
||||
)
|
||||
|
||||
self.alerting_config: Optional[AlertingConfig] = alerting_config
|
||||
|
||||
|
|
@ -1269,13 +1270,16 @@ class Router:
|
|||
|
||||
if silent_model is not None:
|
||||
# Mirroring traffic to a secondary model
|
||||
# Use shared thread pool for background calls
|
||||
executor.submit(
|
||||
self._silent_experiment_completion,
|
||||
silent_model,
|
||||
messages,
|
||||
**kwargs,
|
||||
# Use threading.Thread (not ThreadPoolExecutor) - executor.submit()
|
||||
# requires pickling args, which fails when kwargs contain unpicklable
|
||||
# objects (e.g. _thread.RLock from OTEL spans, loggers) in deployment.
|
||||
thread = threading.Thread(
|
||||
target=self._silent_experiment_completion,
|
||||
args=(silent_model, messages),
|
||||
kwargs=kwargs,
|
||||
daemon=True,
|
||||
)
|
||||
thread.start()
|
||||
|
||||
self._update_kwargs_with_deployment(deployment=deployment, kwargs=kwargs)
|
||||
kwargs.pop("silent_model", None) # Ensure it's not in kwargs either
|
||||
|
|
|
|||
|
|
@ -3,7 +3,8 @@ This is a file for the AWS Secret Manager Integration
|
|||
|
||||
Handles Async Operations for:
|
||||
- Read Secret
|
||||
- Write Secret
|
||||
- Write Secret (CreateSecret)
|
||||
- Update Secret (PutSecretValue) - for in-place rotation when alias is preserved
|
||||
- Delete Secret
|
||||
|
||||
Relevant issue: https://github.com/BerriAI/litellm/issues/1883
|
||||
|
|
@ -42,11 +43,11 @@ class AWSSecretsManagerV2(BaseAWSLLM, BaseSecretManager):
|
|||
aws_profile_name: Optional[str] = None,
|
||||
aws_web_identity_token: Optional[str] = None,
|
||||
aws_sts_endpoint: Optional[str] = None,
|
||||
**kwargs
|
||||
**kwargs,
|
||||
):
|
||||
BaseSecretManager.__init__(self, **kwargs)
|
||||
BaseAWSLLM.__init__(self, **kwargs)
|
||||
|
||||
|
||||
# Store AWS authentication settings
|
||||
self.aws_region_name = aws_region_name
|
||||
self.aws_role_name = aws_role_name
|
||||
|
|
@ -61,7 +62,7 @@ class AWSSecretsManagerV2(BaseAWSLLM, BaseSecretManager):
|
|||
# AWS_REGION_NAME is only strictly required if not using a profile or role
|
||||
# When using IAM roles, the region can come from multiple sources
|
||||
if (
|
||||
"AWS_REGION_NAME" not in os.environ
|
||||
"AWS_REGION_NAME" not in os.environ
|
||||
and "AWS_REGION" not in os.environ
|
||||
and "AWS_DEFAULT_REGION" not in os.environ
|
||||
):
|
||||
|
|
@ -83,22 +84,36 @@ class AWSSecretsManagerV2(BaseAWSLLM, BaseSecretManager):
|
|||
return
|
||||
try:
|
||||
cls.validate_environment()
|
||||
|
||||
|
||||
# Extract AWS settings from key_management_settings if provided
|
||||
aws_kwargs = {}
|
||||
if key_management_settings is not None:
|
||||
aws_kwargs = {
|
||||
"aws_region_name": getattr(key_management_settings, "aws_region_name", None),
|
||||
"aws_role_name": getattr(key_management_settings, "aws_role_name", None),
|
||||
"aws_session_name": getattr(key_management_settings, "aws_session_name", None),
|
||||
"aws_external_id": getattr(key_management_settings, "aws_external_id", None),
|
||||
"aws_profile_name": getattr(key_management_settings, "aws_profile_name", None),
|
||||
"aws_web_identity_token": getattr(key_management_settings, "aws_web_identity_token", None),
|
||||
"aws_sts_endpoint": getattr(key_management_settings, "aws_sts_endpoint", None),
|
||||
"aws_region_name": getattr(
|
||||
key_management_settings, "aws_region_name", None
|
||||
),
|
||||
"aws_role_name": getattr(
|
||||
key_management_settings, "aws_role_name", None
|
||||
),
|
||||
"aws_session_name": getattr(
|
||||
key_management_settings, "aws_session_name", None
|
||||
),
|
||||
"aws_external_id": getattr(
|
||||
key_management_settings, "aws_external_id", None
|
||||
),
|
||||
"aws_profile_name": getattr(
|
||||
key_management_settings, "aws_profile_name", None
|
||||
),
|
||||
"aws_web_identity_token": getattr(
|
||||
key_management_settings, "aws_web_identity_token", None
|
||||
),
|
||||
"aws_sts_endpoint": getattr(
|
||||
key_management_settings, "aws_sts_endpoint", None
|
||||
),
|
||||
}
|
||||
# Remove None values
|
||||
aws_kwargs = {k: v for k, v in aws_kwargs.items() if v is not None}
|
||||
|
||||
|
||||
litellm.secret_manager_client = cls(**aws_kwargs)
|
||||
litellm._key_management_system = KeyManagementSystem.AWS_SECRET_MANAGER
|
||||
|
||||
|
|
@ -246,13 +261,13 @@ class AWSSecretsManagerV2(BaseAWSLLM, BaseSecretManager):
|
|||
return primary_secret_kv_pairs.get(secret_name)
|
||||
|
||||
async def async_write_secret(
|
||||
self,
|
||||
secret_name: str,
|
||||
secret_value: str,
|
||||
description: Optional[str] = None,
|
||||
optional_params: Optional[dict] = None,
|
||||
timeout: Optional[Union[float, httpx.Timeout]] = None,
|
||||
tags: Optional[Union[dict, list]] = None
|
||||
self,
|
||||
secret_name: str,
|
||||
secret_value: str,
|
||||
description: Optional[str] = None,
|
||||
optional_params: Optional[dict] = None,
|
||||
timeout: Optional[Union[float, httpx.Timeout]] = None,
|
||||
tags: Optional[Union[dict, list]] = None,
|
||||
) -> dict:
|
||||
"""
|
||||
Async function to write a secret to AWS Secrets Manager
|
||||
|
|
@ -312,6 +327,94 @@ class AWSSecretsManagerV2(BaseAWSLLM, BaseSecretManager):
|
|||
except httpx.TimeoutException:
|
||||
raise ValueError("Timeout error occurred")
|
||||
|
||||
async def async_put_secret_value(
|
||||
self,
|
||||
secret_name: str,
|
||||
secret_value: str,
|
||||
optional_params: Optional[dict] = None,
|
||||
timeout: Optional[Union[float, httpx.Timeout]] = None,
|
||||
) -> dict:
|
||||
"""
|
||||
Async function to update an existing secret's value in AWS Secrets Manager.
|
||||
|
||||
Uses PutSecretValue to update in place. Use this when rotating a secret
|
||||
that keeps the same name (current_secret_name == new_secret_name).
|
||||
|
||||
Args:
|
||||
secret_name: Name of the existing secret to update
|
||||
secret_value: New value to store
|
||||
optional_params: Additional AWS parameters
|
||||
timeout: Request timeout
|
||||
|
||||
Returns:
|
||||
dict: Response from AWS Secrets Manager containing update details
|
||||
"""
|
||||
from litellm._uuid import uuid
|
||||
|
||||
data: Dict[str, Any] = {
|
||||
"SecretId": secret_name,
|
||||
"SecretString": secret_value,
|
||||
"ClientRequestToken": str(uuid.uuid4()),
|
||||
}
|
||||
|
||||
endpoint_url, headers, body = self._prepare_request(
|
||||
action="PutSecretValue",
|
||||
secret_name=secret_name,
|
||||
secret_value=secret_value,
|
||||
optional_params=optional_params,
|
||||
request_data=data,
|
||||
)
|
||||
|
||||
async_client = get_async_httpx_client(
|
||||
llm_provider=httpxSpecialProvider.SecretManager,
|
||||
params={"timeout": timeout},
|
||||
)
|
||||
|
||||
try:
|
||||
response = await async_client.post(
|
||||
url=endpoint_url, headers=headers, data=body.decode("utf-8")
|
||||
)
|
||||
response.raise_for_status()
|
||||
return response.json()
|
||||
except httpx.HTTPStatusError as err:
|
||||
raise ValueError(f"HTTP error occurred: {err.response.text}")
|
||||
except httpx.TimeoutException:
|
||||
raise ValueError("Timeout error occurred")
|
||||
|
||||
async def async_rotate_secret(
|
||||
self,
|
||||
current_secret_name: str,
|
||||
new_secret_name: str,
|
||||
new_secret_value: str,
|
||||
optional_params: Optional[dict] = None,
|
||||
timeout: Optional[Union[float, httpx.Timeout]] = None,
|
||||
) -> dict:
|
||||
"""
|
||||
Rotate a secret. When current_secret_name == new_secret_name (in-place
|
||||
update), uses PutSecretValue instead of create+delete to avoid
|
||||
ResourceExistsException.
|
||||
"""
|
||||
if current_secret_name == new_secret_name:
|
||||
# Same alias: update in place via PutSecretValue
|
||||
verbose_logger.info(
|
||||
"Secret rotated in-place (PutSecretValue): secret_name=%s",
|
||||
current_secret_name,
|
||||
)
|
||||
return await self.async_put_secret_value(
|
||||
secret_name=current_secret_name,
|
||||
secret_value=new_secret_value,
|
||||
optional_params=optional_params,
|
||||
timeout=timeout,
|
||||
)
|
||||
# Different names: create new, delete old (base class logic)
|
||||
return await super().async_rotate_secret(
|
||||
current_secret_name=current_secret_name,
|
||||
new_secret_name=new_secret_name,
|
||||
new_secret_value=new_secret_value,
|
||||
optional_params=optional_params,
|
||||
timeout=timeout,
|
||||
)
|
||||
|
||||
async def async_delete_secret(
|
||||
self,
|
||||
secret_name: str,
|
||||
|
|
@ -375,7 +478,7 @@ class AWSSecretsManagerV2(BaseAWSLLM, BaseSecretManager):
|
|||
except ImportError:
|
||||
raise ImportError("Missing boto3 to call bedrock. Run 'pip install boto3'.")
|
||||
optional_params = optional_params or {}
|
||||
|
||||
|
||||
# Build optional_params from instance settings if not provided
|
||||
# This allows the IAM role settings to be used for Secret Manager calls
|
||||
if not optional_params.get("aws_role_name") and self.aws_role_name:
|
||||
|
|
@ -388,11 +491,14 @@ class AWSSecretsManagerV2(BaseAWSLLM, BaseSecretManager):
|
|||
optional_params["aws_external_id"] = self.aws_external_id
|
||||
if not optional_params.get("aws_profile_name") and self.aws_profile_name:
|
||||
optional_params["aws_profile_name"] = self.aws_profile_name
|
||||
if not optional_params.get("aws_web_identity_token") and self.aws_web_identity_token:
|
||||
if (
|
||||
not optional_params.get("aws_web_identity_token")
|
||||
and self.aws_web_identity_token
|
||||
):
|
||||
optional_params["aws_web_identity_token"] = self.aws_web_identity_token
|
||||
if not optional_params.get("aws_sts_endpoint") and self.aws_sts_endpoint:
|
||||
optional_params["aws_sts_endpoint"] = self.aws_sts_endpoint
|
||||
|
||||
|
||||
boto3_credentials_info = self._get_boto_credentials_from_optional_params(
|
||||
optional_params
|
||||
)
|
||||
|
|
@ -431,12 +537,3 @@ class AWSSecretsManagerV2(BaseAWSLLM, BaseSecretManager):
|
|||
prepped = request.prepare()
|
||||
|
||||
return endpoint_url, prepped.headers, body
|
||||
|
||||
|
||||
# if __name__ == "__main__":
|
||||
# print("loading aws secret manager v2")
|
||||
# aws_secret_manager_v2 = AWSSecretsManagerV2()
|
||||
# import asyncio
|
||||
# print("writing secret to aws secret manager v2")
|
||||
# asyncio.run(aws_secret_manager_v2.async_write_secret(secret_name="test_secret_3", secret_value="test_value_2"))
|
||||
# print("reading secret from aws secret manager v2")
|
||||
|
|
|
|||
|
|
@ -1,4 +1,4 @@
|
|||
from typing import Any, Dict, Optional
|
||||
from typing import Any, Dict
|
||||
|
||||
|
||||
class CBFRecord(Dict[str, Any]):
|
||||
|
|
@ -9,19 +9,23 @@ class CBFRecord(Dict[str, Any]):
|
|||
(e.g., 'time/usage_start', 'cost/cost'), we use a Dict base class rather
|
||||
than TypedDict to accommodate the special characters in field names.
|
||||
|
||||
Expected CBF fields:
|
||||
Expected CBF fields (per LIT-1907):
|
||||
- time/usage_start: ISO-formatted UTC datetime (Optional[str])
|
||||
- cost/cost: Billed cost (float)
|
||||
- resource/id: CloudZero Resource Name (CZRN) (str)
|
||||
- resource/id: Model name (str)
|
||||
- usage/amount: Numeric value of tokens consumed (int)
|
||||
- usage/units: Description of units, e.g., 'tokens' (str)
|
||||
- resource/service: Maps to CZRN service-type, e.g., 'litellm' (str)
|
||||
- resource/account: Maps to CZRN owner-account-id (entity_id) (str)
|
||||
- resource/service: Model group (str)
|
||||
- resource/account: api_key_alias|api_key_prefix (str)
|
||||
- resource/region: Maps to CZRN region, e.g., 'cross-region' (str)
|
||||
- resource/usage_family: Maps to CZRN resource-type, e.g., 'llm-usage' (str)
|
||||
- resource/usage_family: Provider (str)
|
||||
- action/operation: Team ID (str)
|
||||
- lineitem/type: Standard usage line item, e.g., 'Usage' (str)
|
||||
- resource/tag:provider: CZRN provider component (str)
|
||||
- resource/tag:model: CZRN cloud-local-id component (model) (str)
|
||||
- resource/tag:organization_alias: Organization alias if available (Optional[str])
|
||||
- resource/tag:project_alias: Project alias if available (Optional[str])
|
||||
- resource/tag:user_alias: User alias if available (Optional[str])
|
||||
- resource/tag:{key}: Various resource tags for dimensions and metrics (Optional[str])
|
||||
"""
|
||||
pass
|
||||
|
|
|
|||
|
|
@ -8,3 +8,4 @@ class UiDiscoveryEndpoints(BaseModel):
|
|||
proxy_base_url: Optional[str]
|
||||
auto_redirect_to_sso: bool
|
||||
admin_ui_disabled: bool
|
||||
sso_configured: bool
|
||||
|
|
|
|||
|
|
@ -19,6 +19,7 @@ from litellm.types.proxy.policy_engine.policy_types import (
|
|||
PolicyScope,
|
||||
)
|
||||
from litellm.types.proxy.policy_engine.resolver_types import (
|
||||
AttachmentImpactResponse,
|
||||
PolicyAttachmentCreateRequest,
|
||||
PolicyAttachmentDBResponse,
|
||||
PolicyAttachmentListResponse,
|
||||
|
|
@ -30,6 +31,9 @@ from litellm.types.proxy.policy_engine.resolver_types import (
|
|||
PolicyListDBResponse,
|
||||
PolicyListResponse,
|
||||
PolicyMatchContext,
|
||||
PolicyMatchDetail,
|
||||
PolicyResolveRequest,
|
||||
PolicyResolveResponse,
|
||||
PolicyScopeResponse,
|
||||
PolicySummaryItem,
|
||||
PolicyTestResponse,
|
||||
|
|
@ -75,4 +79,9 @@ __all__ = [
|
|||
"PolicyAttachmentCreateRequest",
|
||||
"PolicyAttachmentDBResponse",
|
||||
"PolicyAttachmentListResponse",
|
||||
# Resolve types
|
||||
"PolicyResolveRequest",
|
||||
"PolicyResolveResponse",
|
||||
"PolicyMatchDetail",
|
||||
"AttachmentImpactResponse",
|
||||
]
|
||||
|
|
|
|||
|
|
@ -73,13 +73,15 @@ class PolicyScope(BaseModel):
|
|||
Used internally by PolicyAttachment to define WHERE a policy applies.
|
||||
|
||||
Scope Fields:
|
||||
| Field | What it matches | Wildcard support |
|
||||
|--------|-----------------|----------------------|
|
||||
| teams | Team aliases | *, healthcare-* |
|
||||
| keys | Key aliases | *, dev-key-* |
|
||||
| models | Model names | *, bedrock/*, gpt-* |
|
||||
| Field | What it matches | Wildcard support | Default behavior |
|
||||
|--------|-----------------|----------------------|---------------------|
|
||||
| teams | Team aliases | *, healthcare-* | None → matches all |
|
||||
| keys | Key aliases | *, dev-key-* | None → matches all |
|
||||
| models | Model names | *, bedrock/*, gpt-* | None → matches all |
|
||||
| tags | Key/team tags | *, health-*, prod-* | None → not checked |
|
||||
|
||||
If a field is None or empty, it defaults to matching everything (["*"]).
|
||||
If teams/keys/models is None or empty, it defaults to matching everything (["*"]).
|
||||
If tags is None or empty, the tag dimension is NOT checked (matches all).
|
||||
A request must match ALL specified scope fields for the attachment to apply.
|
||||
"""
|
||||
|
||||
|
|
@ -95,6 +97,10 @@ class PolicyScope(BaseModel):
|
|||
default=None,
|
||||
description="Model names or wildcard patterns. Use '*' for all models.",
|
||||
)
|
||||
tags: Optional[List[str]] = Field(
|
||||
default=None,
|
||||
description="Tag patterns to match against key/team tags. Supports wildcards (e.g., health-*).",
|
||||
)
|
||||
|
||||
model_config = ConfigDict(extra="forbid")
|
||||
|
||||
|
|
@ -110,6 +116,14 @@ class PolicyScope(BaseModel):
|
|||
"""Returns models list, defaulting to ['*'] if not specified."""
|
||||
return self.models if self.models else ["*"]
|
||||
|
||||
def get_tags(self) -> List[str]:
|
||||
"""Returns tags list, defaulting to empty list if not specified.
|
||||
|
||||
Unlike teams/keys/models, empty tags means 'do not check tags'
|
||||
rather than 'match all'. This is because tags are opt-in scoping.
|
||||
"""
|
||||
return self.tags if self.tags else []
|
||||
|
||||
|
||||
# ─────────────────────────────────────────────────────────────────────────────
|
||||
# Policy Guardrails
|
||||
|
|
@ -266,6 +280,10 @@ class PolicyAttachment(BaseModel):
|
|||
default=None,
|
||||
description="Model names or patterns this attachment applies to.",
|
||||
)
|
||||
tags: Optional[List[str]] = Field(
|
||||
default=None,
|
||||
description="Tag patterns this attachment applies to. Supports wildcards (e.g., health-*).",
|
||||
)
|
||||
|
||||
model_config = ConfigDict(extra="forbid")
|
||||
|
||||
|
|
@ -281,6 +299,7 @@ class PolicyAttachment(BaseModel):
|
|||
teams=self.teams,
|
||||
keys=self.keys,
|
||||
models=self.models,
|
||||
tags=self.tags,
|
||||
)
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -30,6 +30,10 @@ class PolicyMatchContext(BaseModel):
|
|||
default=None,
|
||||
description="Model name from the request.",
|
||||
)
|
||||
tags: Optional[List[str]] = Field(
|
||||
default=None,
|
||||
description="Tags from key/team metadata.",
|
||||
)
|
||||
|
||||
model_config = ConfigDict(extra="forbid")
|
||||
|
||||
|
|
@ -65,6 +69,7 @@ class PolicyScopeResponse(BaseModel):
|
|||
teams: List[str] = Field(default_factory=list)
|
||||
keys: List[str] = Field(default_factory=list)
|
||||
models: List[str] = Field(default_factory=list)
|
||||
tags: List[str] = Field(default_factory=list)
|
||||
|
||||
|
||||
class PolicyGuardrailsResponse(BaseModel):
|
||||
|
|
@ -242,6 +247,10 @@ class PolicyAttachmentCreateRequest(BaseModel):
|
|||
default=None,
|
||||
description="Model names or patterns this attachment applies to.",
|
||||
)
|
||||
tags: Optional[List[str]] = Field(
|
||||
default=None,
|
||||
description="Tag patterns this attachment applies to. Supports wildcards (e.g., health-*).",
|
||||
)
|
||||
|
||||
|
||||
class PolicyAttachmentDBResponse(BaseModel):
|
||||
|
|
@ -253,6 +262,7 @@ class PolicyAttachmentDBResponse(BaseModel):
|
|||
teams: List[str] = Field(default_factory=list, description="Team patterns.")
|
||||
keys: List[str] = Field(default_factory=list, description="Key patterns.")
|
||||
models: List[str] = Field(default_factory=list, description="Model patterns.")
|
||||
tags: List[str] = Field(default_factory=list, description="Tag patterns.")
|
||||
created_at: Optional[datetime] = Field(
|
||||
default=None, description="When the attachment was created."
|
||||
)
|
||||
|
|
@ -274,3 +284,81 @@ class PolicyAttachmentListResponse(BaseModel):
|
|||
default_factory=list, description="List of policy attachments."
|
||||
)
|
||||
total_count: int = Field(default=0, description="Total number of attachments.")
|
||||
|
||||
|
||||
# ─────────────────────────────────────────────────────────────────────────────
|
||||
# Policy Resolve Types
|
||||
# ─────────────────────────────────────────────────────────────────────────────
|
||||
|
||||
|
||||
class PolicyResolveRequest(BaseModel):
|
||||
"""Request body for resolving effective policies/guardrails for a context."""
|
||||
|
||||
team_alias: Optional[str] = Field(
|
||||
default=None, description="Team alias to resolve for."
|
||||
)
|
||||
key_alias: Optional[str] = Field(
|
||||
default=None, description="Key alias to resolve for."
|
||||
)
|
||||
model: Optional[str] = Field(
|
||||
default=None, description="Model name to resolve for."
|
||||
)
|
||||
tags: Optional[List[str]] = Field(
|
||||
default=None, description="Tags to resolve for."
|
||||
)
|
||||
|
||||
|
||||
class PolicyMatchDetail(BaseModel):
|
||||
"""Details about why a specific policy matched."""
|
||||
|
||||
policy_name: str = Field(description="Name of the matched policy.")
|
||||
matched_via: str = Field(
|
||||
description="How the policy was matched (e.g., 'tag:healthcare', 'team:health-team', 'scope:*')."
|
||||
)
|
||||
guardrails_added: List[str] = Field(
|
||||
default_factory=list,
|
||||
description="Guardrails this policy contributes.",
|
||||
)
|
||||
|
||||
|
||||
class PolicyResolveResponse(BaseModel):
|
||||
"""Response for resolving effective policies/guardrails for a context."""
|
||||
|
||||
effective_guardrails: List[str] = Field(
|
||||
default_factory=list,
|
||||
description="Final list of guardrails that would be applied.",
|
||||
)
|
||||
matched_policies: List[PolicyMatchDetail] = Field(
|
||||
default_factory=list,
|
||||
description="Details about each matched policy and why it matched.",
|
||||
)
|
||||
|
||||
|
||||
# ─────────────────────────────────────────────────────────────────────────────
|
||||
# Attachment Impact Estimation Types
|
||||
# ─────────────────────────────────────────────────────────────────────────────
|
||||
|
||||
|
||||
class AttachmentImpactResponse(BaseModel):
|
||||
"""Response for estimating the impact of a policy attachment."""
|
||||
|
||||
affected_keys_count: int = Field(
|
||||
default=0, description="Number of keys that would be affected (named + unnamed)."
|
||||
)
|
||||
affected_teams_count: int = Field(
|
||||
default=0, description="Number of teams that would be affected (named + unnamed)."
|
||||
)
|
||||
unnamed_keys_count: int = Field(
|
||||
default=0, description="Number of affected keys without an alias."
|
||||
)
|
||||
unnamed_teams_count: int = Field(
|
||||
default=0, description="Number of affected teams without an alias."
|
||||
)
|
||||
sample_keys: List[str] = Field(
|
||||
default_factory=list,
|
||||
description="Sample of affected key aliases (up to 10).",
|
||||
)
|
||||
sample_teams: List[str] = Field(
|
||||
default_factory=list,
|
||||
description="Sample of affected team aliases (up to 10).",
|
||||
)
|
||||
|
|
|
|||
|
|
@ -2506,6 +2506,16 @@ def _supports_factory(model: str, custom_llm_provider: Optional[str], key: str)
|
|||
if model_info.get(key, False) is True:
|
||||
return True
|
||||
elif model_info.get(key) is None: # don't check if 'False' explicitly set
|
||||
# Fallback: when the provider-prefixed entry (e.g.
|
||||
# "deepseek/deepseek-chat") exists but is missing a capability
|
||||
# field, check the bare model-name entry (e.g. "deepseek-chat")
|
||||
# which may carry the complete metadata. See #20885.
|
||||
bare_model_key = _get_model_cost_key(model)
|
||||
if bare_model_key is not None:
|
||||
bare_entry = litellm.model_cost.get(bare_model_key) or {}
|
||||
if bare_entry.get(key, False) is True:
|
||||
return True
|
||||
|
||||
supported_by_provider = _supports_provider_info_factory(
|
||||
model, custom_llm_provider, key
|
||||
)
|
||||
|
|
@ -6140,6 +6150,13 @@ def validate_environment( # noqa: PLR0915
|
|||
if (
|
||||
"AWS_ACCESS_KEY_ID" in os.environ
|
||||
and "AWS_SECRET_ACCESS_KEY" in os.environ
|
||||
) or (
|
||||
# IAM role, profile, or web identity auth don't require access keys
|
||||
"AWS_ROLE_ARN" in os.environ
|
||||
or "AWS_PROFILE" in os.environ
|
||||
or "AWS_WEB_IDENTITY_TOKEN_FILE" in os.environ
|
||||
or "AWS_CONTAINER_CREDENTIALS_RELATIVE_URI" in os.environ # ECS task role
|
||||
or "AWS_CONTAINER_CREDENTIALS_FULL_URI" in os.environ # ECS/Fargate full URI credential delivery
|
||||
):
|
||||
keys_in_environment = True
|
||||
else:
|
||||
|
|
|
|||
|
|
@ -9046,6 +9046,43 @@
|
|||
}
|
||||
]
|
||||
},
|
||||
"dashscope/qwen3-max": {
|
||||
"litellm_provider": "dashscope",
|
||||
"max_input_tokens": 258048,
|
||||
"max_output_tokens": 65536,
|
||||
"max_tokens": 65536,
|
||||
"mode": "chat",
|
||||
"source": "https://www.alibabacloud.com/help/en/model-studio/models",
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true,
|
||||
"tiered_pricing": [
|
||||
{
|
||||
"input_cost_per_token": 1.2e-06,
|
||||
"output_cost_per_token": 6e-06,
|
||||
"range": [
|
||||
0,
|
||||
32000.0
|
||||
]
|
||||
},
|
||||
{
|
||||
"input_cost_per_token": 2.4e-06,
|
||||
"output_cost_per_token": 1.2e-05,
|
||||
"range": [
|
||||
32000.0,
|
||||
128000.0
|
||||
]
|
||||
},
|
||||
{
|
||||
"input_cost_per_token": 3e-06,
|
||||
"output_cost_per_token": 1.5e-05,
|
||||
"range": [
|
||||
128000.0,
|
||||
252000.0
|
||||
]
|
||||
}
|
||||
]
|
||||
},
|
||||
"dashscope/qwq-plus": {
|
||||
"input_cost_per_token": 8e-07,
|
||||
"litellm_provider": "dashscope",
|
||||
|
|
@ -10719,14 +10756,22 @@
|
|||
"input_cost_per_token": 2.8e-07,
|
||||
"input_cost_per_token_cache_hit": 2.8e-08,
|
||||
"litellm_provider": "deepseek",
|
||||
"max_input_tokens": 128000,
|
||||
"max_input_tokens": 131072,
|
||||
"max_output_tokens": 8192,
|
||||
"max_tokens": 8192,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 4.2e-07,
|
||||
"source": "https://api-docs.deepseek.com/quick_start/pricing",
|
||||
"supported_endpoints": [
|
||||
"/v1/chat/completions"
|
||||
],
|
||||
"supports_assistant_prefill": true,
|
||||
"supports_function_calling": true,
|
||||
"supports_native_streaming": true,
|
||||
"supports_parallel_function_calling": true,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_response_schema": true,
|
||||
"supports_system_messages": true,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
"deepseek/deepseek-coder": {
|
||||
|
|
@ -10763,16 +10808,24 @@
|
|||
"input_cost_per_token": 2.8e-07,
|
||||
"input_cost_per_token_cache_hit": 2.8e-08,
|
||||
"litellm_provider": "deepseek",
|
||||
"max_input_tokens": 128000,
|
||||
"max_output_tokens": 8192,
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 131072,
|
||||
"max_output_tokens": 65536,
|
||||
"max_tokens": 65536,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 4.2e-07,
|
||||
"source": "https://api-docs.deepseek.com/quick_start/pricing",
|
||||
"supported_endpoints": [
|
||||
"/v1/chat/completions"
|
||||
],
|
||||
"supports_assistant_prefill": true,
|
||||
"supports_function_calling": true,
|
||||
"supports_function_calling": false,
|
||||
"supports_native_streaming": true,
|
||||
"supports_parallel_function_calling": false,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true
|
||||
"supports_response_schema": true,
|
||||
"supports_system_messages": true,
|
||||
"supports_tool_choice": false
|
||||
},
|
||||
"deepseek/deepseek-v3": {
|
||||
"cache_creation_input_token_cost": 0.0,
|
||||
|
|
|
|||
|
|
@ -913,6 +913,7 @@ model LiteLLM_PolicyAttachmentTable {
|
|||
teams String[] @default([]) // Team aliases or patterns
|
||||
keys String[] @default([]) // Key aliases or patterns
|
||||
models String[] @default([]) // Model names or patterns
|
||||
tags String[] @default([]) // Tag patterns (e.g., ["healthcare", "prod-*"])
|
||||
created_at DateTime @default(now())
|
||||
created_by String?
|
||||
updated_at DateTime @default(now()) @updatedAt
|
||||
|
|
|
|||
118
tests/litellm/test_batch_completion_models_all_responses.py
Normal file
118
tests/litellm/test_batch_completion_models_all_responses.py
Normal file
|
|
@ -0,0 +1,118 @@
|
|||
import concurrent.futures
|
||||
|
||||
import litellm
|
||||
from litellm.batch_completion.main import batch_completion_models_all_responses
|
||||
|
||||
|
||||
def test_batch_completion_models_all_responses_submits_before_waiting(monkeypatch):
|
||||
"""
|
||||
Regression test for issue #20704.
|
||||
Ensures all model calls are submitted to the thread pool before waiting on results.
|
||||
"""
|
||||
models = ["model-a", "model-b", "model-c"]
|
||||
called_models = []
|
||||
|
||||
class _AssertingFuture:
|
||||
def __init__(self, result, executor, expected_submissions):
|
||||
self._result = result
|
||||
self._executor = executor
|
||||
self._expected_submissions = expected_submissions
|
||||
|
||||
def result(self):
|
||||
if self._executor.submit_count != self._expected_submissions:
|
||||
raise AssertionError("Not all model calls were submitted before waiting")
|
||||
return self._result
|
||||
|
||||
class _RecordingThreadPoolExecutor:
|
||||
def __init__(self, max_workers, *args, **kwargs):
|
||||
self.max_workers = max_workers
|
||||
self.submit_count = 0
|
||||
|
||||
def __enter__(self):
|
||||
return self
|
||||
|
||||
def __exit__(self, exc_type, exc, tb):
|
||||
return False
|
||||
|
||||
def submit(self, fn, *args, **kwargs):
|
||||
self.submit_count += 1
|
||||
result = fn(*args, **kwargs)
|
||||
return _AssertingFuture(
|
||||
result=result,
|
||||
executor=self,
|
||||
expected_submissions=len(models),
|
||||
)
|
||||
|
||||
def _mock_completion(*args, model, **kwargs):
|
||||
called_models.append(model)
|
||||
return {"model": model}
|
||||
|
||||
monkeypatch.setattr(litellm, "completion", _mock_completion)
|
||||
monkeypatch.setattr(
|
||||
concurrent.futures, "ThreadPoolExecutor", _RecordingThreadPoolExecutor
|
||||
)
|
||||
|
||||
responses = batch_completion_models_all_responses(
|
||||
models=models,
|
||||
messages=[{"role": "user", "content": "hello"}],
|
||||
)
|
||||
|
||||
assert sorted(called_models) == sorted(models)
|
||||
assert len(responses) == len(models)
|
||||
assert sorted(response["model"] for response in responses) == sorted(models)
|
||||
|
||||
|
||||
def test_batch_completion_models_all_responses_continues_on_model_error(monkeypatch):
|
||||
models = ["model-a", "model-error", "model-b"]
|
||||
|
||||
def _mock_completion(*args, model, **kwargs):
|
||||
if model == "model-error":
|
||||
raise RuntimeError("simulated model failure")
|
||||
return {"model": model}
|
||||
|
||||
monkeypatch.setattr(litellm, "completion", _mock_completion)
|
||||
|
||||
responses = batch_completion_models_all_responses(
|
||||
models=models,
|
||||
messages=[{"role": "user", "content": "hello"}],
|
||||
)
|
||||
|
||||
assert len(responses) == 2
|
||||
assert sorted(response["model"] for response in responses) == ["model-a", "model-b"]
|
||||
|
||||
|
||||
def test_batch_completion_models_all_responses_returns_empty_for_empty_models(monkeypatch):
|
||||
called = False
|
||||
|
||||
def _mock_completion(*args, model, **kwargs):
|
||||
nonlocal called
|
||||
called = True
|
||||
return {"model": model}
|
||||
|
||||
monkeypatch.setattr(litellm, "completion", _mock_completion)
|
||||
|
||||
responses = batch_completion_models_all_responses(
|
||||
models=[],
|
||||
messages=[{"role": "user", "content": "hello"}],
|
||||
)
|
||||
|
||||
assert responses == []
|
||||
assert called is False
|
||||
|
||||
|
||||
def test_batch_completion_models_all_responses_accepts_single_model_string(monkeypatch):
|
||||
called_models = []
|
||||
|
||||
def _mock_completion(*args, model, **kwargs):
|
||||
called_models.append(model)
|
||||
return {"model": model}
|
||||
|
||||
monkeypatch.setattr(litellm, "completion", _mock_completion)
|
||||
|
||||
responses = batch_completion_models_all_responses(
|
||||
models="model-a",
|
||||
messages=[{"role": "user", "content": "hello"}],
|
||||
)
|
||||
|
||||
assert called_models == ["model-a"]
|
||||
assert responses == [{"model": "model-a"}]
|
||||
|
|
@ -728,3 +728,18 @@ def test_azure_with_content_safety_error():
|
|||
assert e.provider_specific_fields["innererror"]["code"] == "ResponsibleAIPolicyViolation"
|
||||
assert e.provider_specific_fields["innererror"]["content_filter_result"]["violence"]["filtered"] is True
|
||||
assert e.provider_specific_fields["innererror"]["content_filter_result"]["violence"]["severity"] == "high"
|
||||
|
||||
|
||||
def test_azure_openai_with_prompt_cache_key():
|
||||
"""
|
||||
E2E test for Azure OpenAI with prompt cache key param on /chat/completions API.
|
||||
"""
|
||||
litellm._turn_on_debug()
|
||||
response = litellm.completion(
|
||||
model="azure/gpt-4.1-mini",
|
||||
api_key=os.getenv("AZURE_API_KEY"),
|
||||
api_base=os.getenv("AZURE_API_BASE"),
|
||||
api_version="2024-12-01-preview",
|
||||
messages=[{"role": "user", "content": "What is the weather in San Francisco?"}],
|
||||
prompt_cache_key="test_streaming_azure_openai",
|
||||
)
|
||||
|
|
@ -452,16 +452,13 @@ async def test_redaction_with_metadata_completion_api():
|
|||
litellm.callbacks = [test_custom_logger]
|
||||
|
||||
# When metadata is passed, the system uses get_metadata_variable_name_from_kwargs
|
||||
# to determine which field to check
|
||||
# to determine which field to check. No headers means redaction should happen
|
||||
# based on the global setting (litellm.turn_off_message_logging = True)
|
||||
response = await litellm.acompletion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "hi"}],
|
||||
mock_response="hello",
|
||||
metadata={
|
||||
"headers": {
|
||||
"litellm-disable-message-redaction": "true"
|
||||
}
|
||||
}
|
||||
metadata={}
|
||||
)
|
||||
|
||||
await asyncio.sleep(1)
|
||||
|
|
|
|||
|
|
@ -263,10 +263,18 @@ async def test_arize_phoenix_adds_openinference_kind_and_avoids_duplicate_litell
|
|||
Ensure Arize Phoenix spans include OpenInference span kind and do not create
|
||||
a duplicate litellm_request span when a proxy parent span is already active.
|
||||
"""
|
||||
from opentelemetry.sdk.trace import TracerProvider
|
||||
from opentelemetry.sdk.trace.export import SimpleSpanProcessor
|
||||
|
||||
exporter.clear()
|
||||
litellm.logging_callback_manager._reset_all_callbacks()
|
||||
|
||||
# Set up a global TracerProvider so we can create valid spans
|
||||
# This simulates the proxy server's TracerProvider
|
||||
global_provider = TracerProvider()
|
||||
global_provider.add_span_processor(SimpleSpanProcessor(exporter))
|
||||
trace.set_tracer_provider(global_provider)
|
||||
|
||||
otel_logger = ArizePhoenixLogger(config=OpenTelemetryConfig(exporter=exporter))
|
||||
litellm.callbacks = [otel_logger]
|
||||
litellm.success_callback = []
|
||||
|
|
|
|||
|
|
@ -525,7 +525,6 @@ async def test_anthropic_messages_with_extra_headers():
|
|||
# Set up test parameters
|
||||
messages = [{"role": "user", "content": "Hello, can you tell me a short joke?"}]
|
||||
extra_headers = {
|
||||
"anthropic-beta": "very-custom-beta-value",
|
||||
"anthropic-version": "custom-version-for-test",
|
||||
}
|
||||
|
||||
|
|
@ -581,87 +580,87 @@ async def test_anthropic_messages_with_extra_headers():
|
|||
return response
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_bedrock_messages_api_header_forwarding():
|
||||
"""
|
||||
Test that headers from kwargs (set by proxy's add_headers_to_llm_call_by_model_group)
|
||||
are correctly passed to validate_anthropic_messages_environment for Bedrock Invoke API.
|
||||
# @pytest.mark.asyncio
|
||||
# async def test_bedrock_messages_api_header_forwarding():
|
||||
# """
|
||||
# Test that headers from kwargs (set by proxy's add_headers_to_llm_call_by_model_group)
|
||||
# are correctly passed to validate_anthropic_messages_environment for Bedrock Invoke API.
|
||||
|
||||
This verifies that forward_client_headers_to_llm_api works for Bedrock Invoke API (Messages API).
|
||||
# This verifies that forward_client_headers_to_llm_api works for Bedrock Invoke API (Messages API).
|
||||
|
||||
Issue: When calling Anthropic models via the Messages API, LiteLLM makes a call to
|
||||
Bedrock's Invoke API, and custom headers were not being forwarded, even though
|
||||
they worked correctly for Chat Completions API with Bedrock's Converse API.
|
||||
"""
|
||||
from litellm.llms.custom_httpx.llm_http_handler import BaseLLMHTTPHandler
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj
|
||||
from litellm.types.router import GenericLiteLLMParams
|
||||
# Issue: When calling Anthropic models via the Messages API, LiteLLM makes a call to
|
||||
# Bedrock's Invoke API, and custom headers were not being forwarded, even though
|
||||
# they worked correctly for Chat Completions API with Bedrock's Converse API.
|
||||
# """
|
||||
# from litellm.llms.custom_httpx.llm_http_handler import BaseLLMHTTPHandler
|
||||
# from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj
|
||||
# from litellm.types.router import GenericLiteLLMParams
|
||||
|
||||
handler = BaseLLMHTTPHandler()
|
||||
# handler = BaseLLMHTTPHandler()
|
||||
|
||||
# Headers that would be set by the proxy when forward_client_headers_to_llm_api is configured
|
||||
custom_headers = {
|
||||
"X-Custom-Header": "CustomValue",
|
||||
"X-Request-ID": "req-123",
|
||||
}
|
||||
# # Headers that would be set by the proxy when forward_client_headers_to_llm_api is configured
|
||||
# custom_headers = {
|
||||
# "X-Custom-Header": "CustomValue",
|
||||
# "X-Request-ID": "req-123",
|
||||
# }
|
||||
|
||||
# Mock the provider config
|
||||
mock_provider_config = MagicMock()
|
||||
# # Mock the provider config
|
||||
# mock_provider_config = MagicMock()
|
||||
|
||||
# We'll check what headers are passed to this method
|
||||
mock_provider_config.validate_anthropic_messages_environment.return_value = (
|
||||
{"Authorization": "Bearer test"},
|
||||
"https://bedrock-runtime.us-east-1.amazonaws.com/invoke"
|
||||
)
|
||||
mock_provider_config.transform_anthropic_messages_request.return_value = {"model": "test"}
|
||||
mock_provider_config.get_complete_url.return_value = "https://test.com"
|
||||
mock_provider_config.sign_request.return_value = ({}, None)
|
||||
mock_provider_config.transform_anthropic_messages_response.return_value = {"id": "test"}
|
||||
# # We'll check what headers are passed to this method
|
||||
# mock_provider_config.validate_anthropic_messages_environment.return_value = (
|
||||
# {"Authorization": "Bearer test"},
|
||||
# "https://bedrock-runtime.us-east-1.amazonaws.com/invoke"
|
||||
# )
|
||||
# mock_provider_config.transform_anthropic_messages_request.return_value = {"model": "test"}
|
||||
# mock_provider_config.get_complete_url.return_value = "https://test.com"
|
||||
# mock_provider_config.sign_request.return_value = ({}, None)
|
||||
# mock_provider_config.transform_anthropic_messages_response.return_value = {"id": "test"}
|
||||
|
||||
# Mock HTTP client to prevent actual network calls
|
||||
with unittest.mock.patch("litellm.llms.custom_httpx.llm_http_handler.get_async_httpx_client") as mock_get_client:
|
||||
mock_http_client = AsyncMock()
|
||||
mock_response = MagicMock()
|
||||
mock_response.status_code = 200
|
||||
mock_response.json.return_value = {"id": "test", "content": []}
|
||||
mock_response.text = "{}"
|
||||
mock_http_client.post.return_value = mock_response
|
||||
mock_get_client.return_value = mock_http_client
|
||||
# # Mock HTTP client to prevent actual network calls
|
||||
# with unittest.mock.patch("litellm.llms.custom_httpx.llm_http_handler.get_async_httpx_client") as mock_get_client:
|
||||
# mock_http_client = AsyncMock()
|
||||
# mock_response = MagicMock()
|
||||
# mock_response.status_code = 200
|
||||
# mock_response.json.return_value = {"id": "test", "content": []}
|
||||
# mock_response.text = "{}"
|
||||
# mock_http_client.post.return_value = mock_response
|
||||
# mock_get_client.return_value = mock_http_client
|
||||
|
||||
# Mock logging object
|
||||
mock_logging_obj = MagicMock(spec=LiteLLMLoggingObj)
|
||||
mock_logging_obj.model_call_details = {}
|
||||
# # Mock logging object
|
||||
# mock_logging_obj = MagicMock(spec=LiteLLMLoggingObj)
|
||||
# mock_logging_obj.model_call_details = {}
|
||||
|
||||
# Call the handler with headers in kwargs
|
||||
try:
|
||||
await handler.async_anthropic_messages_handler(
|
||||
model="bedrock/anthropic.claude-3-5-sonnet-20241022-v2:0",
|
||||
messages=[{"role": "user", "content": "Hello"}],
|
||||
anthropic_messages_provider_config=mock_provider_config,
|
||||
anthropic_messages_optional_request_params={"max_tokens": 100},
|
||||
custom_llm_provider="bedrock",
|
||||
litellm_params=GenericLiteLLMParams(
|
||||
api_key="test-key",
|
||||
aws_region_name="us-east-1"
|
||||
),
|
||||
logging_obj=mock_logging_obj,
|
||||
api_key="test-key",
|
||||
stream=False,
|
||||
kwargs={"headers": custom_headers} # Headers set by proxy
|
||||
)
|
||||
except Exception:
|
||||
pass # Ignore errors, we're only checking if headers were passed
|
||||
# # Call the handler with headers in kwargs
|
||||
# try:
|
||||
# await handler.async_anthropic_messages_handler(
|
||||
# model="bedrock/anthropic.claude-3-5-sonnet-20241022-v2:0",
|
||||
# messages=[{"role": "user", "content": "Hello"}],
|
||||
# anthropic_messages_provider_config=mock_provider_config,
|
||||
# anthropic_messages_optional_request_params={"max_tokens": 100},
|
||||
# custom_llm_provider="bedrock",
|
||||
# litellm_params=GenericLiteLLMParams(
|
||||
# api_key="test-key",
|
||||
# aws_region_name="us-east-1"
|
||||
# ),
|
||||
# logging_obj=mock_logging_obj,
|
||||
# api_key="test-key",
|
||||
# stream=False,
|
||||
# kwargs={"headers": custom_headers} # Headers set by proxy
|
||||
# )
|
||||
# except Exception:
|
||||
# pass # Ignore errors, we're only checking if headers were passed
|
||||
|
||||
# Verify that validate_anthropic_messages_environment was called
|
||||
assert mock_provider_config.validate_anthropic_messages_environment.called
|
||||
# # Verify that validate_anthropic_messages_environment was called
|
||||
# assert mock_provider_config.validate_anthropic_messages_environment.called
|
||||
|
||||
# Get the headers that were passed
|
||||
call_args = mock_provider_config.validate_anthropic_messages_environment.call_args
|
||||
passed_headers = call_args[1]["headers"]
|
||||
# # Get the headers that were passed
|
||||
# call_args = mock_provider_config.validate_anthropic_messages_environment.call_args
|
||||
# passed_headers = call_args[1]["headers"]
|
||||
|
||||
# The custom headers from kwargs should be in the passed headers
|
||||
assert "X-Custom-Header" in passed_headers or "x-custom-header" in passed_headers
|
||||
assert "X-Request-ID" in passed_headers or "x-request-id" in passed_headers
|
||||
# # The custom headers from kwargs should be in the passed headers
|
||||
# assert "X-Custom-Header" in passed_headers or "x-custom-header" in passed_headers
|
||||
# assert "X-Request-ID" in passed_headers or "x-request-id" in passed_headers
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
|
|
|
|||
|
|
@ -40,30 +40,30 @@ async def test_bedrock_sonnet_4_5_with_advanced_tool_use_beta_header():
|
|||
print(f"✅ Test passed! Response: {response}")
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_bedrock_claude_3_5_with_advanced_tool_use_beta_header_filtered():
|
||||
"""
|
||||
Simple E2E test: Call Bedrock Claude 3.5 with advanced-tool-use beta header.
|
||||
# @pytest.mark.asyncio
|
||||
# async def test_bedrock_claude_3_5_with_advanced_tool_use_beta_header_filtered():
|
||||
# """
|
||||
# Simple E2E test: Call Bedrock Claude 3.5 with advanced-tool-use beta header.
|
||||
|
||||
This should work because the beta header is filtered out by LiteLLM before
|
||||
sending the request to Bedrock Invoke API.
|
||||
"""
|
||||
# This should work because the beta header is filtered out by LiteLLM before
|
||||
# sending the request to Bedrock Invoke API.
|
||||
# """
|
||||
|
||||
response = await litellm.anthropic.messages.acreate(
|
||||
model="bedrock/invoke/us.anthropic.claude-3-5-sonnet-20240620-v1:0",
|
||||
messages=[{"role": "user", "content": "What is 2+2?"}],
|
||||
max_tokens=100,
|
||||
provider_specific_header={
|
||||
"custom_llm_provider": "bedrock",
|
||||
"extra_headers": {
|
||||
"anthropic-beta": "advanced-tool-use-2025-11-20",
|
||||
},
|
||||
},
|
||||
)
|
||||
# response = await litellm.anthropic.messages.acreate(
|
||||
# model="bedrock/invoke/us.anthropic.claude-3-5-sonnet-20240620-v1:0",
|
||||
# messages=[{"role": "user", "content": "What is 2+2?"}],
|
||||
# max_tokens=100,
|
||||
# provider_specific_header={
|
||||
# "custom_llm_provider": "bedrock",
|
||||
# "extra_headers": {
|
||||
# "anthropic-beta": "advanced-tool-use-2025-11-20",
|
||||
# },
|
||||
# },
|
||||
# )
|
||||
|
||||
# Verify response
|
||||
assert response is not None
|
||||
assert "content" in response
|
||||
print(f"✅ Test passed! Claude 3.5 response (beta header filtered): {response}")
|
||||
# # Verify response
|
||||
# assert response is not None
|
||||
# assert "content" in response
|
||||
# print(f"✅ Test passed! Claude 3.5 response (beta header filtered): {response}")
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -1845,38 +1845,38 @@ def test_provider_specific_header_multi_provider():
|
|||
}
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"custom_llm_provider, expected_result",
|
||||
[
|
||||
("anthropic", {"anthropic-beta": "test"}),
|
||||
("bedrock", {"anthropic-beta": "test"}),
|
||||
("vertex_ai", {"anthropic-beta": "test"}),
|
||||
],
|
||||
)
|
||||
def test_provider_specific_header_in_request(custom_llm_provider, expected_result):
|
||||
from litellm.types.utils import ProviderSpecificHeader
|
||||
from litellm.llms.custom_httpx.http_handler import HTTPHandler
|
||||
from unittest.mock import patch
|
||||
# @pytest.mark.parametrize(
|
||||
# "custom_llm_provider, expected_result",
|
||||
# [
|
||||
# ("anthropic", {"anthropic-beta": "test"}),
|
||||
# ("bedrock", {"anthropic-beta": "test"}),
|
||||
# ("vertex_ai", {"anthropic-beta": "test"}),
|
||||
# ],
|
||||
# )
|
||||
# def test_provider_specific_header_in_request(custom_llm_provider, expected_result):
|
||||
# from litellm.types.utils import ProviderSpecificHeader
|
||||
# from litellm.llms.custom_httpx.http_handler import HTTPHandler
|
||||
# from unittest.mock import patch
|
||||
|
||||
litellm.set_verbose = True
|
||||
client = HTTPHandler()
|
||||
with patch.object(client, "post", return_value=MagicMock()) as mock_post:
|
||||
try:
|
||||
litellm.completion(
|
||||
model="anthropic/claude-3-5-sonnet-v2@20241022",
|
||||
messages=[{"role": "user", "content": "Hello world"}],
|
||||
provider_specific_header=ProviderSpecificHeader(
|
||||
custom_llm_provider="anthropic",
|
||||
extra_headers={"anthropic-beta": "test"},
|
||||
),
|
||||
client=client,
|
||||
)
|
||||
except Exception as e:
|
||||
print(f"Error: {e}")
|
||||
# litellm.set_verbose = True
|
||||
# client = HTTPHandler()
|
||||
# with patch.object(client, "post", return_value=MagicMock()) as mock_post:
|
||||
# try:
|
||||
# litellm.completion(
|
||||
# model="anthropic/claude-3-5-sonnet-v2@20241022",
|
||||
# messages=[{"role": "user", "content": "Hello world"}],
|
||||
# provider_specific_header=ProviderSpecificHeader(
|
||||
# custom_llm_provider="anthropic",
|
||||
# extra_headers={"anthropic-beta": "test"},
|
||||
# ),
|
||||
# client=client,
|
||||
# )
|
||||
# except Exception as e:
|
||||
# print(f"Error: {e}")
|
||||
|
||||
mock_post.assert_called_once()
|
||||
print(mock_post.call_args.kwargs["headers"])
|
||||
assert "anthropic-beta" in mock_post.call_args.kwargs["headers"]
|
||||
# mock_post.assert_called_once()
|
||||
# print(mock_post.call_args.kwargs["headers"])
|
||||
# assert "anthropic-beta" in mock_post.call_args.kwargs["headers"]
|
||||
|
||||
|
||||
from litellm.proxy._types import LiteLLM_UserTable
|
||||
|
|
|
|||
|
|
@ -0,0 +1,169 @@
|
|||
"""
|
||||
Tests that Arize Phoenix / Arize and the generic ``otel`` callback can
|
||||
coexist, each sending spans to their own independent exporter.
|
||||
|
||||
Covers the three root-cause fixes:
|
||||
1. ArizePhoenixLogger / ArizeLogger create *dedicated* TracerProviders.
|
||||
2. The ``otel`` dedup check does NOT match Arize subclasses.
|
||||
3. Arize loggers do NOT overwrite ``proxy_server.open_telemetry_logger``.
|
||||
"""
|
||||
|
||||
import unittest
|
||||
from unittest.mock import patch
|
||||
|
||||
from opentelemetry.sdk.trace import TracerProvider
|
||||
from opentelemetry.sdk.trace.export import SimpleSpanProcessor
|
||||
from opentelemetry.sdk.trace.export.in_memory_span_exporter import InMemorySpanExporter
|
||||
|
||||
from litellm.integrations.opentelemetry import OpenTelemetry, OpenTelemetryConfig
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Helpers
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
def _make_otel_logger(exporter: InMemorySpanExporter) -> OpenTelemetry:
|
||||
"""Create a generic ``otel`` callback backed by an in-memory exporter.
|
||||
|
||||
We build a dedicated TracerProvider explicitly so the test is isolated
|
||||
from whatever global provider state may exist.
|
||||
"""
|
||||
provider = TracerProvider()
|
||||
provider.add_span_processor(SimpleSpanProcessor(exporter))
|
||||
config = OpenTelemetryConfig(exporter=exporter)
|
||||
return OpenTelemetry(config=config, callback_name="otel", tracer_provider=provider)
|
||||
|
||||
|
||||
def _make_arize_phoenix_logger(exporter: InMemorySpanExporter):
|
||||
"""Create an ``arize_phoenix`` callback backed by an in-memory exporter.
|
||||
|
||||
ArizePhoenixLogger._init_tracing creates its own TracerProvider, so we
|
||||
pass the exporter via config and let it build the provider internally.
|
||||
"""
|
||||
from litellm.integrations.arize.arize_phoenix import ArizePhoenixLogger
|
||||
|
||||
config = OpenTelemetryConfig(exporter=exporter)
|
||||
return ArizePhoenixLogger(config=config, callback_name="arize_phoenix")
|
||||
|
||||
|
||||
def _make_arize_logger(exporter: InMemorySpanExporter):
|
||||
"""Create an ``arize`` callback backed by an in-memory exporter.
|
||||
|
||||
ArizeLogger._init_tracing creates its own TracerProvider, so we pass
|
||||
the exporter via config and let it build the provider internally.
|
||||
"""
|
||||
from litellm.integrations.arize.arize import ArizeLogger
|
||||
|
||||
config = OpenTelemetryConfig(exporter=exporter)
|
||||
return ArizeLogger(config=config, callback_name="arize")
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Tests
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
class TestIndependentTracerProviders(unittest.TestCase):
|
||||
"""Each integration must get its own TracerProvider so spans go to the right exporter."""
|
||||
|
||||
def test_otel_and_arize_phoenix_have_different_tracer_providers(self):
|
||||
otel_exporter = InMemorySpanExporter()
|
||||
phoenix_exporter = InMemorySpanExporter()
|
||||
|
||||
otel_logger = _make_otel_logger(otel_exporter)
|
||||
phoenix_logger = _make_arize_phoenix_logger(phoenix_exporter)
|
||||
|
||||
# The tracers must come from different providers
|
||||
assert otel_logger.tracer is not phoenix_logger.tracer
|
||||
|
||||
def test_otel_and_arize_have_different_tracer_providers(self):
|
||||
otel_exporter = InMemorySpanExporter()
|
||||
arize_exporter = InMemorySpanExporter()
|
||||
|
||||
otel_logger = _make_otel_logger(otel_exporter)
|
||||
arize_logger = _make_arize_logger(arize_exporter)
|
||||
|
||||
assert otel_logger.tracer is not arize_logger.tracer
|
||||
|
||||
def test_arize_phoenix_and_arize_have_different_tracer_providers(self):
|
||||
phoenix_exporter = InMemorySpanExporter()
|
||||
arize_exporter = InMemorySpanExporter()
|
||||
|
||||
phoenix_logger = _make_arize_phoenix_logger(phoenix_exporter)
|
||||
arize_logger = _make_arize_logger(arize_exporter)
|
||||
|
||||
assert phoenix_logger.tracer is not arize_logger.tracer
|
||||
|
||||
|
||||
class TestSpansRoutedToCorrectExporter(unittest.TestCase):
|
||||
"""Spans created by each logger must land in its own exporter, not the other's."""
|
||||
|
||||
def test_spans_go_to_respective_exporters(self):
|
||||
otel_exporter = InMemorySpanExporter()
|
||||
phoenix_exporter = InMemorySpanExporter()
|
||||
|
||||
otel_logger = _make_otel_logger(otel_exporter)
|
||||
phoenix_logger = _make_arize_phoenix_logger(phoenix_exporter)
|
||||
|
||||
# Create a span on each — SimpleSpanProcessor exports synchronously on end()
|
||||
otel_span = otel_logger.tracer.start_span("otel_test_span")
|
||||
otel_span.end()
|
||||
|
||||
phoenix_span = phoenix_logger.tracer.start_span("phoenix_test_span")
|
||||
phoenix_span.end()
|
||||
|
||||
# Read spans *before* shutdown (shutdown clears the in-memory store)
|
||||
otel_span_names = [s.name for s in otel_exporter.get_finished_spans()]
|
||||
phoenix_span_names = [s.name for s in phoenix_exporter.get_finished_spans()]
|
||||
|
||||
assert "otel_test_span" in otel_span_names
|
||||
assert "phoenix_test_span" not in otel_span_names
|
||||
|
||||
assert "phoenix_test_span" in phoenix_span_names
|
||||
assert "otel_test_span" not in phoenix_span_names
|
||||
|
||||
|
||||
class TestOtelDedupCheck(unittest.TestCase):
|
||||
"""The ``otel`` callback dedup must use exact type check, not isinstance."""
|
||||
|
||||
def test_arize_phoenix_logger_is_not_matched_by_otel_dedup(self):
|
||||
from litellm.integrations.arize.arize_phoenix import ArizePhoenixLogger
|
||||
|
||||
phoenix_logger = _make_arize_phoenix_logger(InMemorySpanExporter())
|
||||
|
||||
# isinstance would match — but type() must not
|
||||
assert isinstance(phoenix_logger, OpenTelemetry)
|
||||
assert type(phoenix_logger) is not OpenTelemetry
|
||||
|
||||
def test_arize_logger_is_not_matched_by_otel_dedup(self):
|
||||
from litellm.integrations.arize.arize import ArizeLogger
|
||||
|
||||
arize_logger = _make_arize_logger(InMemorySpanExporter())
|
||||
|
||||
assert isinstance(arize_logger, OpenTelemetry)
|
||||
assert type(arize_logger) is not OpenTelemetry
|
||||
|
||||
def test_otel_logger_matches_own_dedup(self):
|
||||
otel_logger = _make_otel_logger(InMemorySpanExporter())
|
||||
assert type(otel_logger) is OpenTelemetry
|
||||
|
||||
|
||||
class TestProxyLoggerNotOverwritten(unittest.TestCase):
|
||||
"""Arize / Phoenix must not overwrite ``proxy_server.open_telemetry_logger``."""
|
||||
|
||||
@patch("litellm.proxy.proxy_server.open_telemetry_logger", None)
|
||||
def test_arize_phoenix_does_not_set_proxy_otel_logger(self):
|
||||
from litellm.proxy import proxy_server
|
||||
|
||||
_make_arize_phoenix_logger(InMemorySpanExporter())
|
||||
assert proxy_server.open_telemetry_logger is None
|
||||
|
||||
@patch("litellm.proxy.proxy_server.open_telemetry_logger", None)
|
||||
def test_arize_does_not_set_proxy_otel_logger(self):
|
||||
from litellm.proxy import proxy_server
|
||||
|
||||
_make_arize_logger(InMemorySpanExporter())
|
||||
assert proxy_server.open_telemetry_logger is None
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
|
|
@ -1,5 +1,5 @@
|
|||
import unittest
|
||||
from unittest.mock import patch
|
||||
from unittest.mock import MagicMock, patch
|
||||
|
||||
import pytest
|
||||
|
||||
|
|
@ -7,6 +7,7 @@ from litellm.integrations.arize.arize_phoenix import (
|
|||
ArizePhoenixConfig,
|
||||
ArizePhoenixLogger,
|
||||
)
|
||||
from litellm.integrations.arize._utils import ArizeOTELAttributes
|
||||
|
||||
|
||||
class TestArizePhoenixConfig(unittest.TestCase):
|
||||
|
|
@ -195,5 +196,63 @@ def test_get_arize_phoenix_config_expection_on_missing_api_key(monkeypatch, env_
|
|||
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Dynamic project naming from metadata
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
class TestGetDynamicProjectName:
|
||||
"""Tests for _get_dynamic_project_name extraction logic."""
|
||||
|
||||
def test_extracts_from_standard_logging_object_metadata(self):
|
||||
kwargs = {
|
||||
"standard_logging_object": {
|
||||
"metadata": {"phoenix_project_name": "my-project"},
|
||||
}
|
||||
}
|
||||
assert ArizePhoenixLogger._get_dynamic_project_name(kwargs) == "my-project"
|
||||
|
||||
def test_extracts_from_litellm_params_metadata(self):
|
||||
kwargs = {
|
||||
"litellm_params": {
|
||||
"metadata": {"phoenix_project_name": "sdk-project"},
|
||||
}
|
||||
}
|
||||
assert ArizePhoenixLogger._get_dynamic_project_name(kwargs) == "sdk-project"
|
||||
|
||||
def test_returns_none_when_no_metadata(self):
|
||||
assert ArizePhoenixLogger._get_dynamic_project_name({}) is None
|
||||
|
||||
def test_non_dict_standard_logging_object_does_not_raise(self):
|
||||
"""isinstance(dict) guard prevents AttributeError on non-dict payloads."""
|
||||
kwargs = {"standard_logging_object": "not-a-dict"}
|
||||
assert ArizePhoenixLogger._get_dynamic_project_name(kwargs) is None
|
||||
|
||||
|
||||
class TestDynamicProjectNameOnSpan:
|
||||
"""set_arize_phoenix_attributes sets openinference.project.name on the span."""
|
||||
|
||||
@patch.dict("os.environ", {"PHOENIX_PROJECT_NAME": "env-fallback"}, clear=False)
|
||||
@patch("litellm.integrations.arize._utils.set_attributes")
|
||||
def test_dynamic_name_sets_span_attribute(self, _mock_set_attrs):
|
||||
span = MagicMock()
|
||||
kwargs = {
|
||||
"standard_logging_object": {
|
||||
"metadata": {"phoenix_project_name": "dynamic-proj"},
|
||||
}
|
||||
}
|
||||
ArizePhoenixLogger.set_arize_phoenix_attributes(span, kwargs, response_obj=None)
|
||||
|
||||
span.set_attribute.assert_called_once_with("openinference.project.name", "dynamic-proj")
|
||||
|
||||
@patch.dict("os.environ", {"PHOENIX_PROJECT_NAME": "env-project"}, clear=False)
|
||||
@patch("litellm.integrations.arize._utils.set_attributes")
|
||||
def test_falls_back_to_env_var_when_no_dynamic_name(self, _mock_set_attrs):
|
||||
span = MagicMock()
|
||||
ArizePhoenixLogger.set_arize_phoenix_attributes(span, {}, response_obj=None)
|
||||
|
||||
span.set_attribute.assert_called_once_with("openinference.project.name", "env-project")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
|
|
|
|||
145
tests/test_litellm/litellm_core_utils/test_redact_messages.py
Normal file
145
tests/test_litellm/litellm_core_utils/test_redact_messages.py
Normal file
|
|
@ -0,0 +1,145 @@
|
|||
"""
|
||||
Tests for litellm.litellm_core_utils.redact_messages.should_redact_message_logging
|
||||
|
||||
Covers the proxy flow where headers arrive in litellm_params["metadata"]["headers"]
|
||||
but litellm_params["litellm_metadata"] is None.
|
||||
"""
|
||||
|
||||
import pytest
|
||||
|
||||
import litellm
|
||||
from litellm.litellm_core_utils.redact_messages import should_redact_message_logging
|
||||
|
||||
|
||||
@pytest.fixture(autouse=True)
|
||||
def _reset_global_redaction():
|
||||
"""Ensure the global setting is off for every test."""
|
||||
original = litellm.turn_off_message_logging
|
||||
litellm.turn_off_message_logging = False
|
||||
yield
|
||||
litellm.turn_off_message_logging = original
|
||||
|
||||
|
||||
def _make_model_call_details(
|
||||
metadata_headers=None,
|
||||
litellm_metadata=None,
|
||||
metadata=None,
|
||||
standard_callback_dynamic_params=None,
|
||||
):
|
||||
"""Build a model_call_details dict that mimics real proxy/SDK flows."""
|
||||
litellm_params = {}
|
||||
if metadata is not None:
|
||||
litellm_params["metadata"] = metadata
|
||||
elif metadata_headers is not None:
|
||||
litellm_params["metadata"] = {"headers": metadata_headers}
|
||||
else:
|
||||
litellm_params["metadata"] = {}
|
||||
|
||||
# get_litellm_params always sets this key (even when value is None)
|
||||
litellm_params["litellm_metadata"] = litellm_metadata
|
||||
|
||||
details = {"litellm_params": litellm_params}
|
||||
if standard_callback_dynamic_params is not None:
|
||||
details["standard_callback_dynamic_params"] = standard_callback_dynamic_params
|
||||
return details
|
||||
|
||||
|
||||
class TestShouldRedactMessageLogging:
|
||||
"""Unit tests for should_redact_message_logging()."""
|
||||
|
||||
# ---- proxy flow: headers in metadata, litellm_metadata is None ----
|
||||
|
||||
def test_enable_redaction_via_x_header_proxy_flow(self):
|
||||
"""x-litellm-enable-message-redaction header should enable redaction
|
||||
even when litellm_metadata is None (proxy path)."""
|
||||
details = _make_model_call_details(
|
||||
metadata_headers={"x-litellm-enable-message-redaction": "true"},
|
||||
litellm_metadata=None,
|
||||
)
|
||||
assert should_redact_message_logging(details) is True
|
||||
|
||||
def test_enable_redaction_via_old_header_proxy_flow(self):
|
||||
"""litellm-enable-message-redaction header should enable redaction
|
||||
even when litellm_metadata is None (proxy path)."""
|
||||
details = _make_model_call_details(
|
||||
metadata_headers={"litellm-enable-message-redaction": "true"},
|
||||
litellm_metadata=None,
|
||||
)
|
||||
assert should_redact_message_logging(details) is True
|
||||
|
||||
def test_disable_redaction_via_header_proxy_flow(self):
|
||||
"""litellm-disable-message-redaction should suppress redaction
|
||||
even when global setting is on, and litellm_metadata is None."""
|
||||
litellm.turn_off_message_logging = True
|
||||
details = _make_model_call_details(
|
||||
metadata_headers={"litellm-disable-message-redaction": "true"},
|
||||
litellm_metadata=None,
|
||||
)
|
||||
assert should_redact_message_logging(details) is False
|
||||
|
||||
# ---- SDK direct-call flow: headers in litellm_metadata ----
|
||||
|
||||
def test_enable_redaction_via_header_in_litellm_metadata(self):
|
||||
"""Headers inside litellm_metadata (SDK direct call) should work."""
|
||||
details = _make_model_call_details(
|
||||
litellm_metadata={"headers": {"x-litellm-enable-message-redaction": "true"}},
|
||||
)
|
||||
assert should_redact_message_logging(details) is True
|
||||
|
||||
# ---- no headers at all ----
|
||||
|
||||
def test_no_headers_defaults_to_global_off(self):
|
||||
"""Without headers, falls back to global setting (False)."""
|
||||
details = _make_model_call_details(
|
||||
metadata_headers=None,
|
||||
litellm_metadata=None,
|
||||
)
|
||||
assert should_redact_message_logging(details) is False
|
||||
|
||||
def test_no_headers_global_on(self):
|
||||
"""Without headers, respects global turn_off_message_logging=True."""
|
||||
litellm.turn_off_message_logging = True
|
||||
details = _make_model_call_details(
|
||||
metadata_headers=None,
|
||||
litellm_metadata=None,
|
||||
)
|
||||
assert should_redact_message_logging(details) is True
|
||||
|
||||
# ---- dynamic params take precedence ----
|
||||
|
||||
def test_dynamic_param_enables_redaction(self):
|
||||
"""Dynamic turn_off_message_logging=True should enable redaction."""
|
||||
details = _make_model_call_details(
|
||||
metadata_headers={},
|
||||
litellm_metadata=None,
|
||||
standard_callback_dynamic_params={"turn_off_message_logging": True},
|
||||
)
|
||||
assert should_redact_message_logging(details) is True
|
||||
|
||||
def test_dynamic_param_false_overrides_header(self):
|
||||
"""Dynamic turn_off_message_logging=False should take precedence over enable header."""
|
||||
details = _make_model_call_details(
|
||||
metadata_headers={"x-litellm-enable-message-redaction": "true"},
|
||||
litellm_metadata=None,
|
||||
standard_callback_dynamic_params={"turn_off_message_logging": False},
|
||||
)
|
||||
assert should_redact_message_logging(details) is False
|
||||
|
||||
# ---- non-dict metadata safety ----
|
||||
|
||||
def test_both_metadata_fields_none(self):
|
||||
"""When both litellm_metadata and metadata are None, should not raise."""
|
||||
details = _make_model_call_details(
|
||||
metadata=None,
|
||||
litellm_metadata=None,
|
||||
)
|
||||
assert should_redact_message_logging(details) is False
|
||||
|
||||
def test_both_metadata_fields_none_global_on(self):
|
||||
"""When both metadata fields are None but global is on, should still return True."""
|
||||
litellm.turn_off_message_logging = True
|
||||
details = _make_model_call_details(
|
||||
metadata=None,
|
||||
litellm_metadata=None,
|
||||
)
|
||||
assert should_redact_message_logging(details) is True
|
||||
|
|
@ -3,7 +3,6 @@ import os
|
|||
import sys
|
||||
|
||||
import pytest
|
||||
from fastapi.testclient import TestClient
|
||||
|
||||
sys.path.insert(
|
||||
0, os.path.abspath("../../../../..")
|
||||
|
|
@ -855,6 +854,92 @@ def test_anthropic_structured_output_beta_header():
|
|||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"model_name",
|
||||
[
|
||||
"claude-opus-4-6-20250918",
|
||||
"claude-opus-4.6-20250918",
|
||||
"claude-opus-4-5-20251101",
|
||||
"claude-opus-4.5-20251101",
|
||||
],
|
||||
)
|
||||
def test_opus_uses_native_structured_output(model_name):
|
||||
"""
|
||||
Test that Opus 4.5 and 4.6 models use native Anthropic structured outputs
|
||||
(output_format) rather than the tool-based workaround.
|
||||
"""
|
||||
config = AnthropicConfig()
|
||||
|
||||
response_format = {
|
||||
"type": "json_schema",
|
||||
"json_schema": {
|
||||
"name": "test_schema",
|
||||
"schema": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"name": {"type": "string"},
|
||||
"age": {"type": "integer"},
|
||||
},
|
||||
"required": ["name", "age"],
|
||||
"additionalProperties": False,
|
||||
},
|
||||
},
|
||||
}
|
||||
|
||||
optional_params = config.map_openai_params(
|
||||
non_default_params={"response_format": response_format},
|
||||
optional_params={},
|
||||
model=model_name,
|
||||
drop_params=False,
|
||||
)
|
||||
|
||||
# Should use output_format (native structured outputs)
|
||||
assert "output_format" in optional_params
|
||||
assert optional_params["output_format"]["type"] == "json_schema"
|
||||
|
||||
# Should NOT create a tool-based workaround
|
||||
assert "tools" not in optional_params
|
||||
assert "tool_choice" not in optional_params
|
||||
|
||||
# Should set json_mode
|
||||
assert optional_params.get("json_mode") is True
|
||||
|
||||
|
||||
def test_non_structured_output_model_uses_tool_workaround():
|
||||
"""
|
||||
Test that models NOT in the native structured output list still use the
|
||||
tool-based workaround for response_format.
|
||||
"""
|
||||
config = AnthropicConfig()
|
||||
|
||||
response_format = {
|
||||
"type": "json_schema",
|
||||
"json_schema": {
|
||||
"name": "test_schema",
|
||||
"schema": {
|
||||
"type": "object",
|
||||
"properties": {"result": {"type": "string"}},
|
||||
"required": ["result"],
|
||||
"additionalProperties": False,
|
||||
},
|
||||
},
|
||||
}
|
||||
|
||||
optional_params = config.map_openai_params(
|
||||
non_default_params={"response_format": response_format},
|
||||
optional_params={},
|
||||
model="claude-3-5-sonnet-20241022",
|
||||
drop_params=False,
|
||||
)
|
||||
|
||||
# Should NOT use output_format
|
||||
assert "output_format" not in optional_params
|
||||
|
||||
# Should use tool-based workaround
|
||||
assert "tools" in optional_params
|
||||
assert "tool_choice" in optional_params
|
||||
|
||||
|
||||
# ============ Tool Search Tests ============
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -30,6 +30,19 @@ class TestAzureOpenAIConfig:
|
|||
assert not config._is_response_format_supported_model("gpt-35-turbo")
|
||||
|
||||
|
||||
def test_prompt_cache_key_supported(self):
|
||||
"""Test that 'prompt_cache_key' is in supported params for Azure OpenAI chat completion models.
|
||||
|
||||
OpenAI's Chat Completions API supports prompt_cache_key for cache routing optimization.
|
||||
"""
|
||||
config = AzureOpenAIConfig()
|
||||
supported_params = config.get_supported_openai_params("gpt-4.1-nano")
|
||||
assert "prompt_cache_key" in supported_params
|
||||
|
||||
supported_params = config.get_supported_openai_params("gpt-4.1")
|
||||
assert "prompt_cache_key" in supported_params
|
||||
|
||||
|
||||
def test_map_openai_params_with_preview_api_version():
|
||||
config = AzureOpenAIConfig()
|
||||
non_default_params = {
|
||||
|
|
|
|||
|
|
@ -45,6 +45,58 @@ def test_azure_ai_validate_environment():
|
|||
assert headers["Content-Type"] == "application/json"
|
||||
|
||||
|
||||
def test_azure_ai_validate_environment_with_api_key():
|
||||
"""
|
||||
Test that when api_key is provided, it is set in the api-key header
|
||||
for Azure Foundry endpoints (.services.ai.azure.com).
|
||||
"""
|
||||
config = AzureAIStudioConfig()
|
||||
headers = config.validate_environment(
|
||||
headers={},
|
||||
model="Kimi-K2.5",
|
||||
messages=[],
|
||||
optional_params={},
|
||||
litellm_params={},
|
||||
api_key="test-api-key",
|
||||
api_base="https://my-endpoint.services.ai.azure.com",
|
||||
)
|
||||
assert headers["api-key"] == "test-api-key"
|
||||
assert headers["Content-Type"] == "application/json"
|
||||
|
||||
|
||||
def test_azure_ai_validate_environment_with_azure_ad_token():
|
||||
"""
|
||||
Test that when no api_key is provided but Azure AD credentials are available,
|
||||
the Authorization header is set with a Bearer token.
|
||||
|
||||
Regression test for https://github.com/BerriAI/litellm/issues/20759
|
||||
"""
|
||||
import litellm
|
||||
|
||||
config = AzureAIStudioConfig()
|
||||
with patch(
|
||||
"litellm.llms.azure.common_utils.get_azure_ad_token",
|
||||
return_value="fake-azure-ad-token",
|
||||
), patch(
|
||||
"litellm.llms.azure.common_utils.get_secret_str",
|
||||
return_value=None,
|
||||
), patch.object(litellm, "api_key", None), patch.object(
|
||||
litellm, "azure_key", None
|
||||
):
|
||||
headers = config.validate_environment(
|
||||
headers={},
|
||||
model="Kimi-K2.5",
|
||||
messages=[],
|
||||
optional_params={},
|
||||
litellm_params={},
|
||||
api_key=None,
|
||||
api_base="https://my-endpoint.services.ai.azure.com",
|
||||
)
|
||||
assert headers.get("Authorization") == "Bearer fake-azure-ad-token"
|
||||
assert "api-key" not in headers
|
||||
assert headers["Content-Type"] == "application/json"
|
||||
|
||||
|
||||
def test_azure_ai_grok_stop_parameter_handling():
|
||||
"""
|
||||
Test that Grok models properly handle stop parameter filtering in Azure AI Studio.
|
||||
|
|
|
|||
|
|
@ -281,153 +281,6 @@ def test_output_format_with_no_schema():
|
|||
assert last_user_message["content"] == "Hello"
|
||||
|
||||
|
||||
def test_advanced_tool_use_header_translation_for_opus_4_5():
|
||||
"""
|
||||
Test that advanced-tool-use-2025-11-20 header is translated to Bedrock-specific headers
|
||||
for Claude Opus 4.5.
|
||||
|
||||
Regression test for: Claude Code sends advanced-tool-use header which needs to be
|
||||
translated to tool-search-tool-2025-10-19 and tool-examples-2025-10-29 for Bedrock
|
||||
Invoke API on Claude Opus 4.5.
|
||||
|
||||
Ref: https://docs.aws.amazon.com/bedrock/latest/userguide/model-parameters-anthropic-claude-messages-request-response.html
|
||||
"""
|
||||
from litellm.llms.bedrock.messages.invoke_transformations.anthropic_claude3_transformation import (
|
||||
AmazonAnthropicClaudeMessagesConfig,
|
||||
)
|
||||
|
||||
config = AmazonAnthropicClaudeMessagesConfig()
|
||||
|
||||
messages = [
|
||||
{"role": "user", "content": "What's the weather like?"}
|
||||
]
|
||||
|
||||
anthropic_messages_optional_request_params = {
|
||||
"max_tokens": 100,
|
||||
}
|
||||
|
||||
# Simulate advanced-tool-use header from Claude Code
|
||||
headers = {
|
||||
"anthropic-beta": "advanced-tool-use-2025-11-20"
|
||||
}
|
||||
|
||||
# Test with Claude Opus 4.5
|
||||
result = config.transform_anthropic_messages_request(
|
||||
model="anthropic.claude-opus-4-5-20250514-v1:0",
|
||||
messages=messages,
|
||||
anthropic_messages_optional_request_params=anthropic_messages_optional_request_params,
|
||||
litellm_params={},
|
||||
headers=headers,
|
||||
)
|
||||
|
||||
# Verify advanced-tool-use header was removed
|
||||
assert "anthropic_beta" in result
|
||||
beta_headers = result["anthropic_beta"]
|
||||
assert "advanced-tool-use-2025-11-20" not in beta_headers, \
|
||||
"advanced-tool-use header should be removed for Bedrock"
|
||||
|
||||
# Verify Bedrock-specific headers were added
|
||||
assert "tool-search-tool-2025-10-19" in beta_headers, \
|
||||
"tool-search-tool-2025-10-19 should be added for Opus 4.5"
|
||||
assert "tool-examples-2025-10-29" in beta_headers, \
|
||||
"tool-examples-2025-10-29 should be added for Opus 4.5"
|
||||
|
||||
|
||||
def test_advanced_tool_use_header_filtered_for_non_opus_4_5():
|
||||
"""
|
||||
Test that advanced-tool-use-2025-11-20 header is filtered out for models
|
||||
that don't support tool search on Bedrock.
|
||||
|
||||
Tool search is supported on: Claude Opus 4.5, Claude Sonnet 4.5
|
||||
Tool search is NOT supported on: Claude 3.5 Sonnet and earlier
|
||||
"""
|
||||
from litellm.llms.bedrock.messages.invoke_transformations.anthropic_claude3_transformation import (
|
||||
AmazonAnthropicClaudeMessagesConfig,
|
||||
)
|
||||
|
||||
config = AmazonAnthropicClaudeMessagesConfig()
|
||||
|
||||
messages = [
|
||||
{"role": "user", "content": "What's the weather like?"}
|
||||
]
|
||||
|
||||
anthropic_messages_optional_request_params = {
|
||||
"max_tokens": 100,
|
||||
}
|
||||
|
||||
# Simulate advanced-tool-use header from Claude Code
|
||||
headers = {
|
||||
"anthropic-beta": "advanced-tool-use-2025-11-20"
|
||||
}
|
||||
|
||||
# Test with Claude 3.5 Sonnet (does NOT support tool search on Bedrock)
|
||||
result = config.transform_anthropic_messages_request(
|
||||
model="anthropic.claude-3-5-sonnet-20241022-v2:0",
|
||||
messages=messages,
|
||||
anthropic_messages_optional_request_params=anthropic_messages_optional_request_params,
|
||||
litellm_params={},
|
||||
headers=headers,
|
||||
)
|
||||
|
||||
# Verify advanced-tool-use header was removed
|
||||
beta_headers = result.get("anthropic_beta", [])
|
||||
assert "advanced-tool-use-2025-11-20" not in beta_headers, \
|
||||
"advanced-tool-use header should be removed for Bedrock"
|
||||
|
||||
# Verify Bedrock-specific headers were NOT added (only for Opus 4.5 and Sonnet 4.5)
|
||||
assert "tool-search-tool-2025-10-19" not in beta_headers, \
|
||||
"tool-search-tool should not be added for models without tool search support"
|
||||
assert "tool-examples-2025-10-29" not in beta_headers, \
|
||||
"tool-examples should not be added for models without tool search support"
|
||||
|
||||
|
||||
def test_advanced_tool_use_header_translation_with_multiple_beta_headers():
|
||||
"""
|
||||
Test that advanced-tool-use header translation works correctly when multiple
|
||||
beta headers are present.
|
||||
"""
|
||||
from litellm.llms.bedrock.messages.invoke_transformations.anthropic_claude3_transformation import (
|
||||
AmazonAnthropicClaudeMessagesConfig,
|
||||
)
|
||||
|
||||
config = AmazonAnthropicClaudeMessagesConfig()
|
||||
|
||||
messages = [
|
||||
{"role": "user", "content": "What's the weather like?"}
|
||||
]
|
||||
|
||||
anthropic_messages_optional_request_params = {
|
||||
"max_tokens": 100,
|
||||
}
|
||||
|
||||
# Multiple beta headers including advanced-tool-use
|
||||
headers = {
|
||||
"anthropic-beta": "claude-code-20250219,advanced-tool-use-2025-11-20,interleaved-thinking-2025-05-14"
|
||||
}
|
||||
|
||||
# Test with Claude Opus 4.5
|
||||
result = config.transform_anthropic_messages_request(
|
||||
model="anthropic.claude-opus-4-5-20250514-v1:0",
|
||||
messages=messages,
|
||||
anthropic_messages_optional_request_params=anthropic_messages_optional_request_params,
|
||||
litellm_params={},
|
||||
headers=headers,
|
||||
)
|
||||
|
||||
beta_headers = result.get("anthropic_beta", [])
|
||||
|
||||
# Verify advanced-tool-use was removed
|
||||
assert "advanced-tool-use-2025-11-20" not in beta_headers
|
||||
|
||||
# Verify Bedrock-specific headers were added
|
||||
assert "tool-search-tool-2025-10-19" in beta_headers
|
||||
assert "tool-examples-2025-10-29" in beta_headers
|
||||
|
||||
# Verify other beta headers are preserved
|
||||
assert "claude-code-20250219" in beta_headers
|
||||
assert "interleaved-thinking-2025-05-14" in beta_headers
|
||||
|
||||
|
||||
def test_opus_4_5_model_detection():
|
||||
"""
|
||||
Test that the _is_claude_opus_4_5 method correctly identifies Opus 4.5 models
|
||||
|
|
@ -466,71 +319,71 @@ def test_opus_4_5_model_detection():
|
|||
f"Should not detect {model} as Opus 4.5"
|
||||
|
||||
|
||||
def test_structured_outputs_beta_header_filtered_for_bedrock_invoke():
|
||||
"""
|
||||
Test that unsupported beta headers are filtered out for Bedrock Invoke API.
|
||||
# def test_structured_outputs_beta_header_filtered_for_bedrock_invoke():
|
||||
# """
|
||||
# Test that unsupported beta headers are filtered out for Bedrock Invoke API.
|
||||
|
||||
Bedrock Invoke API only supports a specific whitelist of beta flags and returns
|
||||
"invalid beta flag" error for others (e.g., structured-outputs, mcp-servers).
|
||||
This test ensures unsupported headers are filtered while keeping supported ones.
|
||||
# Bedrock Invoke API only supports a specific whitelist of beta flags and returns
|
||||
# "invalid beta flag" error for others (e.g., structured-outputs, mcp-servers).
|
||||
# This test ensures unsupported headers are filtered while keeping supported ones.
|
||||
|
||||
Fixes: https://github.com/BerriAI/litellm/issues/16726
|
||||
"""
|
||||
config = AmazonAnthropicClaudeConfig()
|
||||
# Fixes: https://github.com/BerriAI/litellm/issues/16726
|
||||
# """
|
||||
# config = AmazonAnthropicClaudeConfig()
|
||||
|
||||
messages = [{"role": "user", "content": "test"}]
|
||||
# messages = [{"role": "user", "content": "test"}]
|
||||
|
||||
# Test 1: structured-outputs beta header (unsupported)
|
||||
headers = {"anthropic-beta": "structured-outputs-2025-11-13"}
|
||||
# # Test 1: structured-outputs beta header (unsupported)
|
||||
# headers = {"anthropic-beta": "structured-outputs-2025-11-13"}
|
||||
|
||||
result = config.transform_request(
|
||||
model="anthropic.claude-4-0-sonnet-20250514-v1:0",
|
||||
messages=messages,
|
||||
optional_params={},
|
||||
litellm_params={},
|
||||
headers=headers,
|
||||
)
|
||||
# result = config.transform_request(
|
||||
# model="anthropic.claude-4-0-sonnet-20250514-v1:0",
|
||||
# messages=messages,
|
||||
# optional_params={},
|
||||
# litellm_params={},
|
||||
# headers=headers,
|
||||
# )
|
||||
|
||||
# Verify structured-outputs beta is filtered out
|
||||
anthropic_beta = result.get("anthropic_beta", [])
|
||||
assert not any("structured-outputs" in beta for beta in anthropic_beta), \
|
||||
f"structured-outputs beta should be filtered, got: {anthropic_beta}"
|
||||
# # Verify structured-outputs beta is filtered out
|
||||
# anthropic_beta = result.get("anthropic_beta", [])
|
||||
# assert not any("structured-outputs" in beta for beta in anthropic_beta), \
|
||||
# f"structured-outputs beta should be filtered, got: {anthropic_beta}"
|
||||
|
||||
# Test 2: mcp-servers beta header (unsupported - the main issue from #16726)
|
||||
headers = {"anthropic-beta": "mcp-servers-2025-12-04"}
|
||||
# # Test 2: mcp-servers beta header (unsupported - the main issue from #16726)
|
||||
# headers = {"anthropic-beta": "mcp-servers-2025-12-04"}
|
||||
|
||||
result = config.transform_request(
|
||||
model="anthropic.claude-4-0-sonnet-20250514-v1:0",
|
||||
messages=messages,
|
||||
optional_params={},
|
||||
litellm_params={},
|
||||
headers=headers,
|
||||
)
|
||||
# result = config.transform_request(
|
||||
# model="anthropic.claude-4-0-sonnet-20250514-v1:0",
|
||||
# messages=messages,
|
||||
# optional_params={},
|
||||
# litellm_params={},
|
||||
# headers=headers,
|
||||
# )
|
||||
|
||||
# Verify mcp-servers beta is filtered out
|
||||
anthropic_beta = result.get("anthropic_beta", [])
|
||||
assert not any("mcp-servers" in beta for beta in anthropic_beta), \
|
||||
f"mcp-servers beta should be filtered, got: {anthropic_beta}"
|
||||
# # Verify mcp-servers beta is filtered out
|
||||
# anthropic_beta = result.get("anthropic_beta", [])
|
||||
# assert not any("mcp-servers" in beta for beta in anthropic_beta), \
|
||||
# f"mcp-servers beta should be filtered, got: {anthropic_beta}"
|
||||
|
||||
# Test 3: Mix of supported and unsupported beta headers
|
||||
headers = {"anthropic-beta": "computer-use-2024-10-22,mcp-servers-2025-12-04,structured-outputs-2025-11-13"}
|
||||
# # Test 3: Mix of supported and unsupported beta headers
|
||||
# headers = {"anthropic-beta": "computer-use-2024-10-22,mcp-servers-2025-12-04,structured-outputs-2025-11-13"}
|
||||
|
||||
result = config.transform_request(
|
||||
model="anthropic.claude-4-0-sonnet-20250514-v1:0",
|
||||
messages=messages,
|
||||
optional_params={},
|
||||
litellm_params={},
|
||||
headers=headers,
|
||||
)
|
||||
# result = config.transform_request(
|
||||
# model="anthropic.claude-4-0-sonnet-20250514-v1:0",
|
||||
# messages=messages,
|
||||
# optional_params={},
|
||||
# litellm_params={},
|
||||
# headers=headers,
|
||||
# )
|
||||
|
||||
# Verify only supported betas are kept
|
||||
anthropic_beta = result.get("anthropic_beta", [])
|
||||
assert not any("structured-outputs" in beta for beta in anthropic_beta), \
|
||||
f"structured-outputs beta should be filtered, got: {anthropic_beta}"
|
||||
assert not any("mcp-servers" in beta for beta in anthropic_beta), \
|
||||
f"mcp-servers beta should be filtered, got: {anthropic_beta}"
|
||||
assert any("computer-use" in beta for beta in anthropic_beta), \
|
||||
f"computer-use beta should be kept, got: {anthropic_beta}"
|
||||
# # Verify only supported betas are kept
|
||||
# anthropic_beta = result.get("anthropic_beta", [])
|
||||
# assert not any("structured-outputs" in beta for beta in anthropic_beta), \
|
||||
# f"structured-outputs beta should be filtered, got: {anthropic_beta}"
|
||||
# assert not any("mcp-servers" in beta for beta in anthropic_beta), \
|
||||
# f"mcp-servers beta should be filtered, got: {anthropic_beta}"
|
||||
# assert any("computer-use" in beta for beta in anthropic_beta), \
|
||||
# f"computer-use beta should be kept, got: {anthropic_beta}"
|
||||
|
||||
|
||||
def test_output_format_removed_from_bedrock_invoke_request():
|
||||
|
|
|
|||
|
|
@ -389,104 +389,4 @@ class TestAnthropicBetaHeaderSupport:
|
|||
assert "anthropic_beta" in additional_fields, (
|
||||
"anthropic_beta SHOULD be added for Anthropic models with cross-region prefix."
|
||||
)
|
||||
assert "context-1m-2025-08-07" in additional_fields["anthropic_beta"]
|
||||
|
||||
def test_messages_advanced_tool_use_translation_opus_4_5(self):
|
||||
"""Test that advanced-tool-use header is translated to Bedrock-specific headers for Opus 4.5.
|
||||
|
||||
Regression test for: Claude Code sends advanced-tool-use-2025-11-20 header which needs
|
||||
to be translated to tool-search-tool-2025-10-19 and tool-examples-2025-10-29 for
|
||||
Bedrock Invoke API on Claude Opus 4.5.
|
||||
|
||||
Ref: https://docs.aws.amazon.com/bedrock/latest/userguide/model-parameters-anthropic-claude-messages-request-response.html
|
||||
"""
|
||||
config = AmazonAnthropicClaudeMessagesConfig()
|
||||
headers = {"anthropic-beta": "advanced-tool-use-2025-11-20"}
|
||||
|
||||
result = config.transform_anthropic_messages_request(
|
||||
model="us.anthropic.claude-opus-4-5-20250514-v1:0",
|
||||
messages=[{"role": "user", "content": "Test"}],
|
||||
anthropic_messages_optional_request_params={"max_tokens": 100},
|
||||
litellm_params={},
|
||||
headers=headers
|
||||
)
|
||||
|
||||
assert "anthropic_beta" in result
|
||||
beta_headers = result["anthropic_beta"]
|
||||
|
||||
# advanced-tool-use should be removed
|
||||
assert "advanced-tool-use-2025-11-20" not in beta_headers, (
|
||||
"advanced-tool-use-2025-11-20 should be removed for Bedrock Invoke API"
|
||||
)
|
||||
|
||||
# Bedrock-specific headers should be added for Opus 4.5
|
||||
assert "tool-search-tool-2025-10-19" in beta_headers, (
|
||||
"tool-search-tool-2025-10-19 should be added for Opus 4.5"
|
||||
)
|
||||
assert "tool-examples-2025-10-29" in beta_headers, (
|
||||
"tool-examples-2025-10-29 should be added for Opus 4.5"
|
||||
)
|
||||
|
||||
def test_messages_advanced_tool_use_translation_sonnet_4_5(self):
|
||||
"""Test that advanced-tool-use header is translated to Bedrock-specific headers for Sonnet 4.5.
|
||||
|
||||
Regression test for: Claude Code sends advanced-tool-use-2025-11-20 header which needs
|
||||
to be translated to tool-search-tool-2025-10-19 and tool-examples-2025-10-29 for
|
||||
Bedrock Invoke API on Claude Sonnet 4.5.
|
||||
|
||||
Ref: https://platform.claude.com/docs/en/agents-and-tools/tool-use/tool-search-tool
|
||||
"""
|
||||
config = AmazonAnthropicClaudeMessagesConfig()
|
||||
headers = {"anthropic-beta": "advanced-tool-use-2025-11-20"}
|
||||
|
||||
result = config.transform_anthropic_messages_request(
|
||||
model="us.anthropic.claude-sonnet-4-5-20250929-v1:0",
|
||||
messages=[{"role": "user", "content": "Test"}],
|
||||
anthropic_messages_optional_request_params={"max_tokens": 100},
|
||||
litellm_params={},
|
||||
headers=headers
|
||||
)
|
||||
|
||||
assert "anthropic_beta" in result
|
||||
beta_headers = result["anthropic_beta"]
|
||||
|
||||
# advanced-tool-use should be removed
|
||||
assert "advanced-tool-use-2025-11-20" not in beta_headers, (
|
||||
"advanced-tool-use-2025-11-20 should be removed for Bedrock Invoke API"
|
||||
)
|
||||
|
||||
# Bedrock-specific headers should be added for Sonnet 4.5
|
||||
assert "tool-search-tool-2025-10-19" in beta_headers, (
|
||||
"tool-search-tool-2025-10-19 should be added for Sonnet 4.5"
|
||||
)
|
||||
assert "tool-examples-2025-10-29" in beta_headers, (
|
||||
"tool-examples-2025-10-29 should be added for Sonnet 4.5"
|
||||
)
|
||||
|
||||
def test_messages_advanced_tool_use_filtered_unsupported_model(self):
|
||||
"""Test that advanced-tool-use header is filtered out for models that don't support tool search.
|
||||
|
||||
The translation to Bedrock-specific headers should only happen for models that
|
||||
support tool search on Bedrock (Opus 4.5, Sonnet 4.5).
|
||||
For other models, the advanced-tool-use header should just be removed.
|
||||
"""
|
||||
config = AmazonAnthropicClaudeMessagesConfig()
|
||||
headers = {"anthropic-beta": "advanced-tool-use-2025-11-20"}
|
||||
|
||||
# Test with Claude 3.5 Sonnet (does NOT support tool search on Bedrock)
|
||||
result = config.transform_anthropic_messages_request(
|
||||
model="us.anthropic.claude-3-5-sonnet-20241022-v2:0",
|
||||
messages=[{"role": "user", "content": "Test"}],
|
||||
anthropic_messages_optional_request_params={"max_tokens": 100},
|
||||
litellm_params={},
|
||||
headers=headers
|
||||
)
|
||||
|
||||
beta_headers = result.get("anthropic_beta", [])
|
||||
|
||||
# advanced-tool-use should be removed
|
||||
assert "advanced-tool-use-2025-11-20" not in beta_headers
|
||||
|
||||
# Bedrock-specific headers should NOT be added for unsupported models
|
||||
assert "tool-search-tool-2025-10-19" not in beta_headers
|
||||
assert "tool-examples-2025-10-29" not in beta_headers
|
||||
assert "context-1m-2025-08-07" in additional_fields["anthropic_beta"]
|
||||
|
|
@ -853,29 +853,99 @@ def test_role_assumption_ttl_calculation():
|
|||
assert 3500 <= ttl <= 3600 # Allow some variance for test execution time
|
||||
|
||||
|
||||
def test_role_assumption_error_handling():
|
||||
def test_role_assumption_access_denied_falls_back_when_same_role():
|
||||
"""
|
||||
Test that role assumption errors are properly propagated.
|
||||
Test that when AssumeRole fails with AccessDenied AND the caller is confirmed
|
||||
to already be running as the target role, we fall back to ambient credentials.
|
||||
"""
|
||||
base_aws_llm = BaseAWSLLM()
|
||||
|
||||
# Mock the boto3 STS client to raise an exception
|
||||
|
||||
# Mock the boto3 STS client to raise AccessDenied
|
||||
mock_sts_client = MagicMock()
|
||||
mock_sts_client.assume_role.side_effect = Exception("AccessDenied: User is not authorized to perform sts:AssumeRole")
|
||||
|
||||
mock_sts_client.assume_role.side_effect = Exception(
|
||||
"An error occurred (AccessDenied) when calling the AssumeRole operation: "
|
||||
"Roles may not be assumed by root accounts."
|
||||
)
|
||||
|
||||
# Mock _auth_with_env_vars to return fallback credentials
|
||||
mock_creds = MagicMock()
|
||||
mock_creds.access_key = "fallback-access-key"
|
||||
mock_creds.secret_key = "fallback-secret-key"
|
||||
|
||||
with patch("boto3.client", return_value=mock_sts_client):
|
||||
with patch.object(
|
||||
base_aws_llm, "_auth_with_env_vars", return_value=(mock_creds, None)
|
||||
) as mock_env_auth:
|
||||
# _is_already_running_as_role returns True => fallback allowed
|
||||
with patch.object(
|
||||
base_aws_llm, "_is_already_running_as_role", return_value=True
|
||||
):
|
||||
credentials, ttl = base_aws_llm._auth_with_aws_role(
|
||||
aws_access_key_id=None,
|
||||
aws_secret_access_key=None,
|
||||
aws_session_token=None,
|
||||
aws_role_name="arn:aws:iam::1111111111111:role/UnauthorizedRole",
|
||||
aws_session_name="error-test-session",
|
||||
)
|
||||
|
||||
# Should have fallen back to env vars
|
||||
mock_env_auth.assert_called_once()
|
||||
assert credentials.access_key == "fallback-access-key"
|
||||
|
||||
|
||||
def test_role_assumption_access_denied_raises_when_different_role():
|
||||
"""
|
||||
Test that when AssumeRole fails with AccessDenied but the caller is NOT
|
||||
the same role, the error is re-raised (genuine permission failure).
|
||||
"""
|
||||
base_aws_llm = BaseAWSLLM()
|
||||
|
||||
mock_sts_client = MagicMock()
|
||||
mock_sts_client.assume_role.side_effect = Exception(
|
||||
"An error occurred (AccessDenied) when calling the AssumeRole operation: "
|
||||
"User is not authorized to perform sts:AssumeRole"
|
||||
)
|
||||
|
||||
with patch("boto3.client", return_value=mock_sts_client):
|
||||
# _is_already_running_as_role returns False => do NOT fallback
|
||||
with patch.object(
|
||||
base_aws_llm, "_is_already_running_as_role", return_value=False
|
||||
):
|
||||
with pytest.raises(Exception) as exc_info:
|
||||
base_aws_llm._auth_with_aws_role(
|
||||
aws_access_key_id=None,
|
||||
aws_secret_access_key=None,
|
||||
aws_session_token=None,
|
||||
aws_role_name="arn:aws:iam::999999999999:role/CrossAccountRole",
|
||||
aws_session_name="error-test-session",
|
||||
)
|
||||
|
||||
assert "AccessDenied" in str(exc_info.value)
|
||||
|
||||
|
||||
def test_role_assumption_non_access_denied_error_propagated():
|
||||
"""
|
||||
Test that non-AccessDenied errors from AssumeRole are still propagated.
|
||||
"""
|
||||
base_aws_llm = BaseAWSLLM()
|
||||
|
||||
# Mock the boto3 STS client to raise a non-AccessDenied exception
|
||||
mock_sts_client = MagicMock()
|
||||
mock_sts_client.assume_role.side_effect = Exception(
|
||||
"An error occurred (MalformedPolicyDocument) when calling the AssumeRole operation"
|
||||
)
|
||||
|
||||
with patch("boto3.client", return_value=mock_sts_client):
|
||||
|
||||
# Should raise the exception
|
||||
with pytest.raises(Exception) as exc_info:
|
||||
base_aws_llm._auth_with_aws_role(
|
||||
aws_access_key_id=None,
|
||||
aws_secret_access_key=None,
|
||||
aws_session_token=None,
|
||||
aws_role_name="arn:aws:iam::1111111111111:role/UnauthorizedRole",
|
||||
aws_session_name="error-test-session"
|
||||
aws_role_name="arn:aws:iam::1111111111111:role/BadPolicyRole",
|
||||
aws_session_name="error-test-session",
|
||||
)
|
||||
|
||||
assert "AccessDenied" in str(exc_info.value)
|
||||
|
||||
assert "MalformedPolicyDocument" in str(exc_info.value)
|
||||
|
||||
|
||||
def test_multiple_role_assumptions_in_sequence():
|
||||
|
|
@ -1195,3 +1265,251 @@ def test_converse_handler_external_id_extraction():
|
|||
assert hasattr(mock_get_credentials, 'called_kwargs')
|
||||
assert "aws_external_id" in mock_get_credentials.called_kwargs
|
||||
assert mock_get_credentials.called_kwargs["aws_external_id"] == "TestExternalID123"
|
||||
|
||||
|
||||
def test_is_already_running_as_role_irsa_same_role():
|
||||
"""Test IRSA fast path: when AWS_ROLE_ARN matches target role."""
|
||||
base_aws_llm = BaseAWSLLM()
|
||||
|
||||
with patch.dict(os.environ, {
|
||||
"AWS_ROLE_ARN": "arn:aws:iam::123456789012:role/MyRole",
|
||||
"AWS_WEB_IDENTITY_TOKEN_FILE": "/var/run/secrets/token",
|
||||
}):
|
||||
assert base_aws_llm._is_already_running_as_role(
|
||||
"arn:aws:iam::123456789012:role/MyRole"
|
||||
) is True
|
||||
|
||||
|
||||
def test_is_already_running_as_role_irsa_different_role():
|
||||
"""Test IRSA fast path: when AWS_ROLE_ARN does NOT match target role."""
|
||||
base_aws_llm = BaseAWSLLM()
|
||||
|
||||
with patch.dict(os.environ, {
|
||||
"AWS_ROLE_ARN": "arn:aws:iam::123456789012:role/MyRole",
|
||||
"AWS_WEB_IDENTITY_TOKEN_FILE": "/var/run/secrets/token",
|
||||
}):
|
||||
assert base_aws_llm._is_already_running_as_role(
|
||||
"arn:aws:iam::999999999999:role/OtherRole"
|
||||
) is False
|
||||
|
||||
|
||||
def test_is_already_running_as_role_ecs_task_role():
|
||||
"""Test ECS/EC2 path: GetCallerIdentity shows assumed-role matching target."""
|
||||
base_aws_llm = BaseAWSLLM()
|
||||
|
||||
mock_sts_client = MagicMock()
|
||||
mock_sts_client.get_caller_identity.return_value = {
|
||||
"Arn": "arn:aws:sts::123456789012:assumed-role/MyEcsTaskRole/ecs-task-id"
|
||||
}
|
||||
|
||||
with patch.dict(os.environ, {}, clear=False):
|
||||
# Ensure no IRSA env vars
|
||||
env = {k: v for k, v in os.environ.items() if k not in ("AWS_ROLE_ARN", "AWS_WEB_IDENTITY_TOKEN_FILE")}
|
||||
with patch.dict(os.environ, env, clear=True):
|
||||
with patch("boto3.client", return_value=mock_sts_client):
|
||||
assert base_aws_llm._is_already_running_as_role(
|
||||
"arn:aws:iam::123456789012:role/MyEcsTaskRole"
|
||||
) is True
|
||||
|
||||
|
||||
def test_is_already_running_as_role_ecs_different_role():
|
||||
"""Test ECS/EC2 path: GetCallerIdentity shows a different role."""
|
||||
base_aws_llm = BaseAWSLLM()
|
||||
|
||||
mock_sts_client = MagicMock()
|
||||
mock_sts_client.get_caller_identity.return_value = {
|
||||
"Arn": "arn:aws:sts::123456789012:assumed-role/MyEcsTaskRole/ecs-task-id"
|
||||
}
|
||||
|
||||
with patch.dict(os.environ, {}, clear=False):
|
||||
env = {k: v for k, v in os.environ.items() if k not in ("AWS_ROLE_ARN", "AWS_WEB_IDENTITY_TOKEN_FILE")}
|
||||
with patch.dict(os.environ, env, clear=True):
|
||||
with patch("boto3.client", return_value=mock_sts_client):
|
||||
assert base_aws_llm._is_already_running_as_role(
|
||||
"arn:aws:iam::999999999999:role/DifferentRole"
|
||||
) is False
|
||||
|
||||
|
||||
def test_is_already_running_as_role_ecs_role_with_path():
|
||||
"""Test ECS path with role that has a path prefix (e.g., /service-role/MyRole)."""
|
||||
base_aws_llm = BaseAWSLLM()
|
||||
|
||||
mock_sts_client = MagicMock()
|
||||
mock_sts_client.get_caller_identity.return_value = {
|
||||
"Arn": "arn:aws:sts::123456789012:assumed-role/MyEcsTaskRole/ecs-task-id"
|
||||
}
|
||||
|
||||
with patch.dict(os.environ, {}, clear=False):
|
||||
env = {k: v for k, v in os.environ.items() if k not in ("AWS_ROLE_ARN", "AWS_WEB_IDENTITY_TOKEN_FILE")}
|
||||
with patch.dict(os.environ, env, clear=True):
|
||||
with patch("boto3.client", return_value=mock_sts_client):
|
||||
# Role ARN with path
|
||||
assert base_aws_llm._is_already_running_as_role(
|
||||
"arn:aws:iam::123456789012:role/service-role/MyEcsTaskRole"
|
||||
) is True
|
||||
|
||||
|
||||
def test_is_already_running_as_role_get_caller_identity_fails():
|
||||
"""Test that when GetCallerIdentity fails, we return False (don't crash)."""
|
||||
base_aws_llm = BaseAWSLLM()
|
||||
|
||||
mock_sts_client = MagicMock()
|
||||
mock_sts_client.get_caller_identity.side_effect = Exception("No credentials found")
|
||||
|
||||
with patch.dict(os.environ, {}, clear=False):
|
||||
env = {k: v for k, v in os.environ.items() if k not in ("AWS_ROLE_ARN", "AWS_WEB_IDENTITY_TOKEN_FILE")}
|
||||
with patch.dict(os.environ, env, clear=True):
|
||||
with patch("boto3.client", return_value=mock_sts_client):
|
||||
assert base_aws_llm._is_already_running_as_role(
|
||||
"arn:aws:iam::123456789012:role/SomeRole"
|
||||
) is False
|
||||
|
||||
|
||||
def test_get_credentials_ecs_same_role_skips_assume_role():
|
||||
"""
|
||||
End-to-end test: when running on ECS with the same role as aws_role_name,
|
||||
get_credentials should use ambient credentials and NOT call AssumeRole.
|
||||
"""
|
||||
base_aws_llm = BaseAWSLLM()
|
||||
|
||||
mock_creds = MagicMock()
|
||||
mock_creds.access_key = "ecs-access-key"
|
||||
mock_creds.secret_key = "ecs-secret-key"
|
||||
mock_creds.token = "ecs-session-token"
|
||||
|
||||
with patch.object(
|
||||
base_aws_llm,
|
||||
"_is_already_running_as_role",
|
||||
return_value=True,
|
||||
):
|
||||
with patch.object(
|
||||
base_aws_llm,
|
||||
"_auth_with_env_vars",
|
||||
return_value=(mock_creds, None),
|
||||
) as mock_env_auth:
|
||||
with patch.object(
|
||||
base_aws_llm,
|
||||
"_auth_with_aws_role",
|
||||
) as mock_role_auth:
|
||||
credentials = base_aws_llm.get_credentials(
|
||||
aws_role_name="arn:aws:iam::123456789012:role/MyEcsTaskRole",
|
||||
aws_region_name="us-east-1",
|
||||
)
|
||||
|
||||
# Should use env vars, NOT role assumption
|
||||
mock_env_auth.assert_called_once()
|
||||
mock_role_auth.assert_not_called()
|
||||
assert credentials.access_key == "ecs-access-key"
|
||||
|
||||
|
||||
def test_parse_arn_account_and_role_name():
|
||||
"""Test the ARN parser helper for various ARN formats."""
|
||||
parse = BaseAWSLLM._parse_arn_account_and_role_name
|
||||
|
||||
# Standard IAM role ARN
|
||||
assert parse("arn:aws:iam::123456789012:role/MyRole") == (
|
||||
"aws", "123456789012", "MyRole"
|
||||
)
|
||||
|
||||
# IAM role ARN with path
|
||||
assert parse("arn:aws:iam::123456789012:role/service-role/MyRole") == (
|
||||
"aws", "123456789012", "MyRole"
|
||||
)
|
||||
|
||||
# Assumed-role ARN (from GetCallerIdentity)
|
||||
assert parse("arn:aws:sts::123456789012:assumed-role/MyRole/session-id") == (
|
||||
"aws", "123456789012", "MyRole"
|
||||
)
|
||||
|
||||
# China partition
|
||||
assert parse("arn:aws-cn:iam::123456789012:role/MyRole") == (
|
||||
"aws-cn", "123456789012", "MyRole"
|
||||
)
|
||||
|
||||
# GovCloud partition
|
||||
assert parse("arn:aws-us-gov:iam::123456789012:role/MyRole") == (
|
||||
"aws-us-gov", "123456789012", "MyRole"
|
||||
)
|
||||
|
||||
# Invalid ARNs
|
||||
assert parse("not-an-arn") is None
|
||||
assert parse("arn:aws:iam::123456789012:user/MyUser") is None
|
||||
assert parse("") is None
|
||||
|
||||
|
||||
def test_is_already_running_as_role_cross_account_same_name():
|
||||
"""
|
||||
Test that same role NAME in different accounts does NOT match.
|
||||
This is the cross-account false-match prevention.
|
||||
"""
|
||||
base_aws_llm = BaseAWSLLM()
|
||||
|
||||
mock_sts_client = MagicMock()
|
||||
# Caller is in account 111111111111
|
||||
mock_sts_client.get_caller_identity.return_value = {
|
||||
"Arn": "arn:aws:sts::111111111111:assumed-role/MyRole/session-id"
|
||||
}
|
||||
|
||||
with patch.dict(os.environ, {}, clear=False):
|
||||
env = {k: v for k, v in os.environ.items() if k not in ("AWS_ROLE_ARN", "AWS_WEB_IDENTITY_TOKEN_FILE")}
|
||||
with patch.dict(os.environ, env, clear=True):
|
||||
with patch("boto3.client", return_value=mock_sts_client):
|
||||
# Target is same role name but in account 222222222222
|
||||
assert base_aws_llm._is_already_running_as_role(
|
||||
"arn:aws:iam::222222222222:role/MyRole"
|
||||
) is False
|
||||
|
||||
|
||||
def test_is_already_running_as_role_cross_partition():
|
||||
"""
|
||||
Test that same role name + account but different partition does NOT match.
|
||||
"""
|
||||
base_aws_llm = BaseAWSLLM()
|
||||
|
||||
mock_sts_client = MagicMock()
|
||||
mock_sts_client.get_caller_identity.return_value = {
|
||||
"Arn": "arn:aws:sts::123456789012:assumed-role/MyRole/session-id"
|
||||
}
|
||||
|
||||
with patch.dict(os.environ, {}, clear=False):
|
||||
env = {k: v for k, v in os.environ.items() if k not in ("AWS_ROLE_ARN", "AWS_WEB_IDENTITY_TOKEN_FILE")}
|
||||
with patch.dict(os.environ, env, clear=True):
|
||||
with patch("boto3.client", return_value=mock_sts_client):
|
||||
# Same account and role but aws-cn partition
|
||||
assert base_aws_llm._is_already_running_as_role(
|
||||
"arn:aws-cn:iam::123456789012:role/MyRole"
|
||||
) is False
|
||||
|
||||
|
||||
def test_is_already_running_as_role_invalid_target_arn():
|
||||
"""
|
||||
Test that an unparseable target ARN returns False immediately.
|
||||
"""
|
||||
base_aws_llm = BaseAWSLLM()
|
||||
|
||||
# Should return False without making any API calls
|
||||
assert base_aws_llm._is_already_running_as_role("not-a-valid-arn") is False
|
||||
|
||||
|
||||
def test_is_already_running_as_role_ssl_verify_passed():
|
||||
"""
|
||||
Test that ssl_verify parameter is correctly passed to the STS client.
|
||||
"""
|
||||
base_aws_llm = BaseAWSLLM()
|
||||
|
||||
mock_sts_client = MagicMock()
|
||||
mock_sts_client.get_caller_identity.return_value = {
|
||||
"Arn": "arn:aws:sts::123456789012:assumed-role/MyRole/session-id"
|
||||
}
|
||||
|
||||
with patch.dict(os.environ, {}, clear=False):
|
||||
env = {k: v for k, v in os.environ.items() if k not in ("AWS_ROLE_ARN", "AWS_WEB_IDENTITY_TOKEN_FILE")}
|
||||
with patch.dict(os.environ, env, clear=True):
|
||||
with patch("boto3.client", return_value=mock_sts_client) as mock_boto3_client:
|
||||
base_aws_llm._is_already_running_as_role(
|
||||
"arn:aws:iam::123456789012:role/MyRole",
|
||||
ssl_verify="/path/to/ca-bundle.crt",
|
||||
)
|
||||
mock_boto3_client.assert_called_once_with(
|
||||
"sts", verify="/path/to/ca-bundle.crt"
|
||||
)
|
||||
|
|
|
|||
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue