mirror of
https://github.com/BerriAI/litellm.git
synced 2026-09-14 23:21:35 +00:00
Merge branch 'main' into fix/redundant-decrption
This commit is contained in:
 yangdx
commit
89a578d893
727 changed files with 22818 additions and 6820 deletions
|
|
@ -638,7 +638,7 @@ jobs:
|
|||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
resource_class: large
|
||||
resource_class: xlarge
|
||||
|
||||
steps:
|
||||
- checkout
|
||||
|
|
@ -682,7 +682,7 @@ jobs:
|
|||
for dir in "${IGNORE_DIRS[@]}"; do
|
||||
IGNORE_ARGS="$IGNORE_ARGS --ignore=$dir"
|
||||
done
|
||||
uv run --no-sync python -m pytest -v tests/llm_translation $IGNORE_ARGS --junitxml=test-results/junit.xml --durations=20 -n 8 --timeout=120 --timeout_method=thread --retries 2 --retry-delay 5
|
||||
uv run --no-sync python -m pytest -v tests/llm_translation $IGNORE_ARGS --junitxml=test-results/junit.xml --durations=20 -n 4 --timeout=120 --timeout_method=thread --retries 2 --retry-delay 5 --max-worker-restart=5
|
||||
no_output_timeout: 15m
|
||||
|
||||
# Store test results
|
||||
|
|
@ -2911,95 +2911,11 @@ jobs:
|
|||
rm -f /tmp/uv-install.sh
|
||||
echo 'export PATH="$HOME/.local/bin:$PATH"' >> "$BASH_ENV"
|
||||
export PATH="$HOME/.local/bin:$PATH"
|
||||
uv tool run --from 'coverage[toml]==7.10.6' coverage combine realtime_translation_coverage ocr_coverage search_coverage mcp_coverage litellm_mcps_tests_coverage logging_coverage audio_coverage local_testing_part1_coverage local_testing_part2_coverage pass_through_unit_tests_coverage batches_coverage guardrails_coverage redis_caching_coverage
|
||||
uv tool run --from 'coverage[toml]==7.10.6' coverage combine realtime_translation_coverage ocr_coverage search_coverage mcp_coverage logging_coverage audio_coverage local_testing_part1_coverage local_testing_part2_coverage pass_through_unit_tests_coverage batches_coverage guardrails_coverage redis_caching_coverage
|
||||
uv tool run --from 'coverage[toml]==7.10.6' coverage xml
|
||||
- codecov/upload:
|
||||
file: ./coverage.xml
|
||||
|
||||
publish_proxy_extras:
|
||||
docker:
|
||||
- image: cimg/python:3.12
|
||||
working_directory: ~/project/litellm-proxy-extras
|
||||
environment:
|
||||
TWINE_USERNAME: __token__
|
||||
|
||||
steps:
|
||||
- checkout:
|
||||
path: ~/project
|
||||
|
||||
- run:
|
||||
name: Check if litellm-proxy-extras dir or pyproject.toml was modified
|
||||
command: |
|
||||
curl -LsSf -o /tmp/uv-install.sh https://astral.sh/uv/0.10.9/install.sh
|
||||
echo "7fc46e39cb97290b57169c0c813a17970585ac519139f19006453c99b5f2f45f /tmp/uv-install.sh" | sha256sum -c -
|
||||
env UV_NO_MODIFY_PATH=1 sh /tmp/uv-install.sh
|
||||
rm -f /tmp/uv-install.sh
|
||||
echo 'export PATH="$HOME/.local/bin:$PATH"' >> "$BASH_ENV"
|
||||
echo 'export PATH="$HOME/.local/bin:$PATH"' >> "$BASH_ENV"
|
||||
export PATH="$HOME/.local/bin:$PATH"
|
||||
# Get current version from pyproject.toml
|
||||
CURRENT_VERSION=$(python -c 'import tomllib; from pathlib import Path; data = tomllib.loads(Path("pyproject.toml").read_text()); print(data["project"]["version"])')
|
||||
|
||||
# Get last published version from PyPI
|
||||
LAST_VERSION=$(curl -s https://pypi.org/pypi/litellm-proxy-extras/json | python -c "import json, sys; print(json.load(sys.stdin)['info']['version'])")
|
||||
|
||||
echo "Current version: $CURRENT_VERSION"
|
||||
echo "Last published version: $LAST_VERSION"
|
||||
|
||||
# Compare versions using Python's packaging.version
|
||||
VERSION_COMPARE=$(uv run --with 'packaging==25.0' python -c "from packaging import version; print(1 if version.parse('$CURRENT_VERSION') < version.parse('$LAST_VERSION') else 0)")
|
||||
|
||||
echo "Version compare: $VERSION_COMPARE"
|
||||
if [ "$VERSION_COMPARE" = "1" ]; then
|
||||
echo "Error: Current version ($CURRENT_VERSION) is less than last published version ($LAST_VERSION)"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
# If versions are equal or current is greater, compare against the published package contents.
|
||||
EXTRACTED_DIR=$(uv run --with "litellm-proxy-extras==$LAST_VERSION" python -c 'import importlib.util; from pathlib import Path; spec = importlib.util.find_spec("litellm_proxy_extras"); assert spec is not None and spec.origin is not None, "litellm_proxy_extras not found in uv-run environment"; print(Path(spec.origin).resolve().parent)')
|
||||
|
||||
# Compare contents
|
||||
if ! diff -r "$EXTRACTED_DIR" ./litellm_proxy_extras; then
|
||||
if [ "$CURRENT_VERSION" = "$LAST_VERSION" ]; then
|
||||
echo "Error: Changes detected in litellm-proxy-extras but version was not bumped"
|
||||
echo "Current version: $CURRENT_VERSION"
|
||||
echo "Last published version: $LAST_VERSION"
|
||||
echo "Changes:"
|
||||
diff -r "$EXTRACTED_DIR" ./litellm_proxy_extras
|
||||
exit 1
|
||||
fi
|
||||
else
|
||||
echo "No changes detected in litellm-proxy-extras. Skipping PyPI publish."
|
||||
circleci step halt
|
||||
fi
|
||||
|
||||
- run:
|
||||
name: Get new version
|
||||
command: |
|
||||
NEW_VERSION=$(python -c 'import tomllib; from pathlib import Path; data = tomllib.loads(Path("pyproject.toml").read_text()); print(data["project"]["version"])')
|
||||
echo "export NEW_VERSION=$NEW_VERSION" >> $BASH_ENV
|
||||
|
||||
- run:
|
||||
name: Check if versions match
|
||||
command: |
|
||||
cd ~/project
|
||||
# Check pyproject.toml
|
||||
CURRENT_VERSION=$(uv run --with 'packaging==25.0' python -c 'import tomllib; from packaging.requirements import Requirement; from pathlib import Path; data = tomllib.loads(Path("pyproject.toml").read_text()); matches = [spec.version for requirement in data["project"]["optional-dependencies"]["proxy"] for parsed in [Requirement(requirement)] if parsed.name == "litellm-proxy-extras" and parsed.specifier for spec in parsed.specifier if spec.operator == "=="]; print(matches[0] if matches else (_ for _ in ()).throw(SystemExit("Could not find exact litellm-proxy-extras pin in project.optional-dependencies.proxy")))')
|
||||
if [ "$CURRENT_VERSION" != "$NEW_VERSION" ]; then
|
||||
echo "Error: Version in pyproject.toml ($CURRENT_VERSION) doesn't match new version ($NEW_VERSION)"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
- run:
|
||||
name: Publish to PyPI
|
||||
command: |
|
||||
echo -e "[pypi]\nusername = $PYPI_PUBLISH_USERNAME\npassword = $PYPI_PUBLISH_PASSWORD" > ~/.pypirc
|
||||
echo 'export PATH="$HOME/.local/bin:$PATH"' >> "$BASH_ENV"
|
||||
export PATH="$HOME/.local/bin:$PATH"
|
||||
rm -rf build dist
|
||||
uv build
|
||||
uv tool run --from 'twine==6.2.0' twine upload --verbose dist/*
|
||||
|
||||
ui_build:
|
||||
docker:
|
||||
- image: cimg/node:20.19
|
||||
|
|
@ -3214,60 +3130,6 @@ jobs:
|
|||
- litellm-docker-database.tar.zst
|
||||
|
||||
|
||||
prisma_schema_sync:
|
||||
machine:
|
||||
image: ubuntu-2204:2023.10.1
|
||||
resource_class: medium
|
||||
working_directory: ~/project
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
- attach_workspace:
|
||||
at: ~/project
|
||||
- run:
|
||||
name: Start PostgreSQL Database
|
||||
command: |
|
||||
docker run -d \
|
||||
--name postgres-db \
|
||||
-e POSTGRES_USER=postgres \
|
||||
-e POSTGRES_PASSWORD=postgres \
|
||||
-e POSTGRES_DB=litellm_schema_sync \
|
||||
-p 5432:5432 \
|
||||
postgres:14
|
||||
- wait_for_service:
|
||||
url: tcp://localhost:5432
|
||||
timeout: "60"
|
||||
- run:
|
||||
name: Load Docker Database Image
|
||||
command: |
|
||||
zstd -d litellm-docker-database.tar.zst --stdout | docker load
|
||||
docker images | grep litellm-docker-database
|
||||
- run:
|
||||
name: Run schema sync via prisma db push
|
||||
command: |
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e DATABASE_URL="postgresql://postgres:postgres@host.docker.internal:5432/litellm_schema_sync" \
|
||||
-e LITELLM_MASTER_KEY="sk-1234" \
|
||||
--name schema-sync \
|
||||
--add-host=host.docker.internal:host-gateway \
|
||||
-v $(pwd)/litellm/proxy/example_config_yaml/simple_config.yaml:/app/config.yaml \
|
||||
litellm-docker-database:ci \
|
||||
--config /app/config.yaml \
|
||||
--port 4000 \
|
||||
--use_prisma_db_push
|
||||
- run:
|
||||
name: Start outputting logs
|
||||
command: docker logs -f schema-sync
|
||||
background: true
|
||||
- wait_for_service:
|
||||
url: http://localhost:4000
|
||||
timeout: "300"
|
||||
- run:
|
||||
name: Stop schema sync container
|
||||
command: docker stop schema-sync
|
||||
|
||||
|
||||
test_bad_database_url:
|
||||
machine:
|
||||
image: ubuntu-2204:2023.10.1
|
||||
|
|
@ -3421,14 +3283,6 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- prisma_schema_sync:
|
||||
requires:
|
||||
- build_docker_database_image
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- e2e_ui_testing:
|
||||
filters:
|
||||
branches:
|
||||
|
|
@ -3688,9 +3542,3 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- publish_proxy_extras:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_release_day_.*/
|
||||
|
|
|
|||
42
.github/workflows/guard-main-branch.yml
vendored
Normal file
42
.github/workflows/guard-main-branch.yml
vendored
Normal file
|
|
@ -0,0 +1,42 @@
|
|||
name: Guard main branch
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches:
|
||||
- main
|
||||
merge_group:
|
||||
|
||||
permissions: {}
|
||||
|
||||
# DO NOT RENAME the job's `name:` — it is referenced by GitHub branch
|
||||
# protection as a required status check on `main`. Renaming silently
|
||||
# breaks the gate.
|
||||
jobs:
|
||||
guard:
|
||||
name: Verify PR source branch
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 2
|
||||
steps:
|
||||
- name: Reject merge_group events
|
||||
if: github.event_name == 'merge_group'
|
||||
run: |
|
||||
echo "::error::Merge queue is not supported for main. Disable merge queue or update this guard."
|
||||
exit 1
|
||||
- name: Check head branch name
|
||||
env:
|
||||
HEAD_REF: ${{ github.head_ref }}
|
||||
HEAD_REPO: ${{ github.event.pull_request.head.repo.full_name }}
|
||||
BASE_REPO: ${{ github.repository }}
|
||||
run: |
|
||||
echo "PR head repo: $HEAD_REPO"
|
||||
echo "PR head branch: $HEAD_REF"
|
||||
if [ "$HEAD_REPO" != "$BASE_REPO" ]; then
|
||||
echo "::error::PRs to main must originate from the canonical repository ($BASE_REPO), not a fork ($HEAD_REPO). External contributors should open PRs against the 'litellm_oss_branch' branch instead."
|
||||
exit 1
|
||||
fi
|
||||
if [ "$HEAD_REF" = "litellm_internal_staging" ] || [[ "$HEAD_REF" == litellm_hotfix_?* ]]; then
|
||||
echo "Allowed source branch."
|
||||
exit 0
|
||||
fi
|
||||
echo "::error::PRs to main must originate from 'litellm_internal_staging' or a 'litellm_hotfix_*' branch. Got: '$HEAD_REF'. If this is a contribution, retarget the PR against 'litellm_oss_branch' instead."
|
||||
exit 1
|
||||
6
.github/workflows/test-linting.yml
vendored
6
.github/workflows/test-linting.yml
vendored
|
|
@ -2,7 +2,11 @@ name: LiteLLM Linting
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
6
.github/workflows/test-litellm-ui-build.yml
vendored
6
.github/workflows/test-litellm-ui-build.yml
vendored
|
|
@ -4,7 +4,11 @@ permissions:
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
jobs:
|
||||
build-ui:
|
||||
|
|
|
|||
6
.github/workflows/test-mcp.yml
vendored
6
.github/workflows/test-mcp.yml
vendored
|
|
@ -2,7 +2,11 @@ name: LiteLLM MCP Tests (folder - tests/mcp_tests)
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
6
.github/workflows/test-model-map.yaml
vendored
6
.github/workflows/test-model-map.yaml
vendored
|
|
@ -2,7 +2,11 @@ name: Validate model_prices_and_context_window.json
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
6
.github/workflows/test-unit-core-utils.yml
vendored
6
.github/workflows/test-unit-core-utils.yml
vendored
|
|
@ -2,7 +2,11 @@ name: "Unit Tests: Core Utilities"
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
|
|
@ -2,7 +2,11 @@ name: "Unit Tests: Documentation Validation"
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
|
|
@ -2,7 +2,11 @@ name: "Unit Tests: Enterprise, Google GenAI & Routing"
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
6
.github/workflows/test-unit-integrations.yml
vendored
6
.github/workflows/test-unit-integrations.yml
vendored
|
|
@ -2,7 +2,11 @@ name: "Unit Tests: Integrations (Callbacks & Logging)"
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
|
|
@ -2,7 +2,11 @@ name: "Unit Tests: LLM Provider Transformations"
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
6
.github/workflows/test-unit-misc.yml
vendored
6
.github/workflows/test-unit-misc.yml
vendored
|
|
@ -2,7 +2,11 @@ name: "Unit Tests: MCP, Secrets, Containers & Misc"
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
6
.github/workflows/test-unit-proxy-auth.yml
vendored
6
.github/workflows/test-unit-proxy-auth.yml
vendored
|
|
@ -2,7 +2,11 @@ name: "Unit Tests: Proxy Auth & Key Management"
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
2
.github/workflows/test-unit-proxy-db.yml
vendored
2
.github/workflows/test-unit-proxy-db.yml
vendored
|
|
@ -3,7 +3,7 @@ name: "Unit Tests: Proxy DB Operations"
|
|||
# Uses DATABASE_URL secret — only runs on trusted branches, not PRs.
|
||||
on:
|
||||
push:
|
||||
branches: [main, "litellm_*"]
|
||||
branches: [main, "litellm_**"]
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
|
|
@ -2,7 +2,11 @@ name: "Unit Tests: Proxy API Endpoints"
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
6
.github/workflows/test-unit-proxy-infra.yml
vendored
6
.github/workflows/test-unit-proxy-infra.yml
vendored
|
|
@ -2,7 +2,11 @@ name: "Unit Tests: Proxy Infrastructure"
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
6
.github/workflows/test-unit-proxy-legacy.yml
vendored
6
.github/workflows/test-unit-proxy-legacy.yml
vendored
|
|
@ -2,7 +2,11 @@ name: "Unit Tests: Proxy Legacy Tests"
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
|
|
@ -2,7 +2,11 @@ name: "Unit Tests: Responses, Caching & Types"
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
2
.github/workflows/test-unit-security.yml
vendored
2
.github/workflows/test-unit-security.yml
vendored
|
|
@ -3,7 +3,7 @@ name: "Unit Tests: Security"
|
|||
# Uses DATABASE_URL secret — only runs on trusted branches, not PRs.
|
||||
on:
|
||||
push:
|
||||
branches: [main, "litellm_*"]
|
||||
branches: [main, "litellm_**"]
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
|
|
|||
8
.github/workflows/test_server_root_path.yml
vendored
8
.github/workflows/test_server_root_path.yml
vendored
|
|
@ -4,12 +4,16 @@ permissions:
|
|||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
branches:
|
||||
- main
|
||||
- litellm_internal_staging
|
||||
- litellm_oss_branch
|
||||
- "litellm_**"
|
||||
|
||||
jobs:
|
||||
test-server-root-path:
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 15
|
||||
timeout-minutes: 30
|
||||
|
||||
strategy:
|
||||
matrix:
|
||||
|
|
|
|||
|
|
@ -9,6 +9,32 @@ This document provides comprehensive instructions for AI agents to generate rele
|
|||
3. **Previous Version Commit Hash** - To compare model pricing changes
|
||||
4. **Reference Release Notes** - Use recent stable releases (v1.76.3-stable, v1.77.2-stable) as templates for consistent formatting
|
||||
|
||||
### Resolving Staging PRs
|
||||
|
||||
The GitHub release page (e.g. `https://github.com/BerriAI/litellm/releases/tag/v1.83.3-stable`) does **not** list the real changelog directly. The "What's Changed" section contains **staging PRs** that each bundle many individual commits/PRs. For example:
|
||||
|
||||
- `Litellm oss staging 03 14 2026 by @RheagalFire in #23686`
|
||||
- `Litellm ryan march 16 by @ryan-crabbe in #23822`
|
||||
|
||||
To get the real changelog, you MUST click into each staging PR (e.g. `#23686`, `#23822`), open its **Commits** tab, and extract every underlying commit/PR (look for the `(#NNNNN)` suffix on commit titles). Those underlying PRs — not the staging PRs — are what get categorized in the release notes. Never treat a staging PR title as a single changelog entry.
|
||||
|
||||
**IMPORTANT — staging PRs are not the complete source.** Some PRs land on the release branch *before* the staging PRs and are therefore not reachable via `gh api /pulls/<staging>/commits`. GitHub's auto-generated "What's Changed" on the release page also misses these. To catch every PR in the release, you MUST additionally walk the full git log range between the previous release's commit and this release's commit:
|
||||
|
||||
```bash
|
||||
git fetch origin --tags
|
||||
git log <prev_release_commit>..<this_release_commit> --oneline | grep -oE '#[0-9]+' | sort -u
|
||||
```
|
||||
|
||||
Union the PR set from the staging-PR walk with the PR set from `git log`. Any PR in `git log` but missing from your staging-expanded set is almost certainly a content PR that merged directly to the release branch — fetch its title/body with `gh pr view <N>` and categorize it. Do not trust the GH release body or the staging PRs alone as the authoritative list.
|
||||
|
||||
**Sanity check for new contributors.** The GH release body's "New Contributors" list is a *floor*, not authoritative. For every PR author who appears in the release (including underlying PRs from staging and PRs found only via `git log`), verify whether they are a first-time contributor by running:
|
||||
|
||||
```bash
|
||||
gh api "search/issues?q=is:pr+author:<login>+repo:BerriAI/litellm+is:merged&sort=created&order=asc" --jq '.items[0] | {n:.number, merged:.closed_at}'
|
||||
```
|
||||
|
||||
If the author's earliest merged PR number matches a PR in this release window, they are a new contributor. If their earliest merged PR predates the previous release tag, they are not. Do not copy the GH release body's list blindly — it can both miss contributors (PRs that merged via an older dev branch) and falsely include contributors whose "first" PR in this window was not actually their first ever.
|
||||
|
||||
## Step-by-Step Process
|
||||
|
||||
### 1. Initial Setup and Analysis
|
||||
|
|
|
|||
366
docs/my-website/blog/claude_opus_4_7/index.md
Normal file
366
docs/my-website/blog/claude_opus_4_7/index.md
Normal file
|
|
@ -0,0 +1,366 @@
|
|||
---
|
||||
slug: claude_opus_4_7
|
||||
title: "Day 0 Support: Claude Opus 4.7"
|
||||
date: 2026-04-16T10:00:00
|
||||
authors:
|
||||
- sameer
|
||||
- ishaan-alt
|
||||
- krrish
|
||||
description: "Day 0 support for Claude Opus 4.7 on LiteLLM AI Gateway - use across Anthropic, Azure, Vertex AI, and Bedrock."
|
||||
tags: [anthropic, claude, opus 4.7]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
LiteLLM now supports [Claude Opus 4.7](https://www.anthropic.com/news/claude-opus-4-7) on Day 0. Use it across Anthropic, Azure, Vertex AI, and Bedrock through the LiteLLM AI Gateway.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
## Docker Image
|
||||
|
||||
```bash
|
||||
docker pull ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.83.3-stable.opus-4.7
|
||||
```
|
||||
|
||||
## Usage - Anthropic
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-7
|
||||
litellm_params:
|
||||
model: anthropic/claude-opus-4-7
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e ANTHROPIC_API_KEY=$ANTHROPIC_API_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.83.3-stable.opus-4.7 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-7",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Azure
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-7
|
||||
litellm_params:
|
||||
model: azure_ai/claude-opus-4-7
|
||||
api_key: os.environ/AZURE_AI_API_KEY
|
||||
api_base: os.environ/AZURE_AI_API_BASE # https://<resource>.services.ai.azure.com
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e AZURE_AI_API_KEY=$AZURE_AI_API_KEY \
|
||||
-e AZURE_AI_API_BASE=$AZURE_AI_API_BASE \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.83.3-stable.opus-4.7 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-7",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Vertex AI
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-7
|
||||
litellm_params:
|
||||
model: vertex_ai/claude-opus-4-7
|
||||
vertex_project: os.environ/VERTEX_PROJECT
|
||||
vertex_location: us-east5
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e VERTEX_PROJECT=$VERTEX_PROJECT \
|
||||
-e GOOGLE_APPLICATION_CREDENTIALS=/app/credentials.json \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
-v $(pwd)/credentials.json:/app/credentials.json \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.83.3-stable.opus-4.7 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-7",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Bedrock
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-7
|
||||
litellm_params:
|
||||
model: bedrock/anthropic.claude-opus-4-7
|
||||
aws_access_key_id: os.environ/AWS_ACCESS_KEY_ID
|
||||
aws_secret_access_key: os.environ/AWS_SECRET_ACCESS_KEY
|
||||
aws_region_name: us-east-1
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e AWS_ACCESS_KEY_ID=$AWS_ACCESS_KEY_ID \
|
||||
-e AWS_SECRET_ACCESS_KEY=$AWS_SECRET_ACCESS_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.83.3-stable.opus-4.7 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-7",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Advanced Features
|
||||
|
||||
### Adaptive Thinking
|
||||
|
||||
:::note
|
||||
When using `reasoning_effort` with Claude Opus 4.7, all values (`low`, `medium`, `high`, `xhigh`) are mapped to `thinking: {type: "adaptive"}`. To use explicit thinking budgets with `type: "enabled"`, pass the native `thinking` parameter directly.
|
||||
:::
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="completions" label="/chat/completions">
|
||||
|
||||
LiteLLM supports adaptive thinking through the `reasoning_effort` parameter:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-7",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Solve this complex problem: What is the optimal strategy for..."
|
||||
}
|
||||
],
|
||||
"reasoning_effort": "high"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="messages" label="/v1/messages">
|
||||
|
||||
Use the `thinking` parameter with `type: "adaptive"` to enable adaptive thinking mode:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'x-api-key: sk-12345' \
|
||||
--header 'content-type: application/json' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-7",
|
||||
"max_tokens": 16000,
|
||||
"thinking": {
|
||||
"type": "adaptive"
|
||||
},
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Explain why the sum of two even numbers is always even."
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Effort Levels
|
||||
|
||||
Claude Opus 4.7 supports four effort levels: `low`, `medium`, `high` (default), and `xhigh`. These give you finer-grained control over how much reasoning the model applies to a task. Pass the effort level via the `output_config` parameter.
|
||||
|
||||
`xhigh` is a new effort level introduced with Opus 4.7 that sits above `high`. The `max` effort level is Claude Opus 4.6 only and is not available on 4.7.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="completions" label="/chat/completions">
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-7",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Explain quantum computing"
|
||||
}
|
||||
],
|
||||
"output_config": {
|
||||
"effort": "xhigh"
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
**Using OpenAI SDK:**
|
||||
|
||||
```python
|
||||
import openai
|
||||
|
||||
client = openai.OpenAI(
|
||||
api_key="your-litellm-key",
|
||||
base_url="http://0.0.0.0:4000"
|
||||
)
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="claude-opus-4-7",
|
||||
messages=[{"role": "user", "content": "Explain quantum computing"}],
|
||||
extra_body={"output_config": {"effort": "xhigh"}}
|
||||
)
|
||||
```
|
||||
|
||||
**Using LiteLLM SDK:**
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="anthropic/claude-opus-4-7",
|
||||
messages=[{"role": "user", "content": "Explain quantum computing"}],
|
||||
output_config={"effort": "xhigh"},
|
||||
)
|
||||
```
|
||||
|
||||
You can combine `reasoning_effort` with `output_config` for even more fine-grained control over the model's behavior.
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="messages" label="/v1/messages">
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'x-api-key: sk-12345' \
|
||||
--header 'content-type: application/json' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-7",
|
||||
"max_tokens": 4096,
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Explain quantum computing"
|
||||
}
|
||||
],
|
||||
"output_config": {
|
||||
"effort": "xhigh"
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
**Effort level guide:**
|
||||
|
||||
| Effort | When to use |
|
||||
|--------|-------------|
|
||||
| `low` | Short, fast responses — simple lookups, formatting, classification |
|
||||
| `medium` | Balanced tradeoff for everyday Q&A and light reasoning |
|
||||
| `high` (default) | Complex reasoning, code generation, analysis |
|
||||
| `xhigh` | Hardest problems — multi-step math, deep research, agentic planning |
|
||||
|
||||
123
docs/my-website/docs/completion/prompt_compression.md
Normal file
123
docs/my-website/docs/completion/prompt_compression.md
Normal file
|
|
@ -0,0 +1,123 @@
|
|||
# Prompt Compression (`compress()`)
|
||||
|
||||
Use `litellm.compress()` to shrink long conversation history before calling `completion()`.
|
||||
|
||||
The function keeps high-relevance and recent context, replaces low-relevance content with lightweight stubs, and returns a retrieval tool so the model can request full content only when needed.
|
||||
|
||||
## Quickstart
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
messages = [
|
||||
{"role": "system", "content": "You are a coding assistant."},
|
||||
{"role": "user", "content": "# auth.py\n" + "def authenticate():\n pass\n" * 2000},
|
||||
{"role": "user", "content": "# utils.py\n" + "def helper():\n pass\n" * 2000},
|
||||
{"role": "user", "content": "Fix the bug in auth.py"},
|
||||
]
|
||||
|
||||
compressed = litellm.compress(
|
||||
messages=messages,
|
||||
model="gpt-4o",
|
||||
compression_trigger=1000,
|
||||
compression_target=500,
|
||||
)
|
||||
|
||||
response = litellm.completion(
|
||||
model="gpt-4o",
|
||||
messages=compressed["messages"],
|
||||
tools=compressed["tools"],
|
||||
)
|
||||
```
|
||||
|
||||
## What It Returns
|
||||
|
||||
`compress()` returns a dictionary with:
|
||||
|
||||
- `messages`: compressed conversation messages
|
||||
- `original_tokens`: token count before compression
|
||||
- `compressed_tokens`: token count after compression
|
||||
- `compression_ratio`: fraction of tokens removed
|
||||
- `cache`: key-value mapping of stub key -> original full content
|
||||
- `tools`: retrieval tool definition (`litellm_content_retrieve`) for on-demand restoration
|
||||
|
||||
## Parameters
|
||||
|
||||
- `messages` (`List[dict]`, required): input conversation messages
|
||||
- `model` (`str`, required): model name used for token counting
|
||||
- `compression_trigger` (`int`, default `200000`): compress only if input token count exceeds this
|
||||
- `compression_target` (`Optional[int]`, default `70% of compression_trigger`): desired post-compression token budget
|
||||
- `embedding_model` (`Optional[str]`): if set, combines BM25 + embedding relevance scoring
|
||||
- `embedding_model_params` (`Optional[dict]`): additional kwargs passed to `litellm.embedding()`
|
||||
- `compression_cache` (`Optional[DualCache]`): optional cache used by embedding scoring
|
||||
|
||||
## Behavior Notes
|
||||
|
||||
- Messages below `compression_trigger` are passed through unchanged.
|
||||
- System messages, the last user message, and the last assistant message are always preserved.
|
||||
- If a relevant message does not fully fit the remaining budget, `compress()` may keep a truncated version of it.
|
||||
- Compressed-out content is never lost; it is stored in `cache` and addressable by `litellm_content_retrieve`.
|
||||
|
||||
## Handling Retrieval Tool Calls
|
||||
|
||||
If the model calls `litellm_content_retrieve`, look up the requested key in `compressed["cache"]` and return that value as tool output.
|
||||
|
||||
```python
|
||||
import json
|
||||
|
||||
tool_call = response.choices[0].message.tool_calls[0]
|
||||
args = json.loads(tool_call.function.arguments)
|
||||
full_content = compressed["cache"][args["key"]]
|
||||
```
|
||||
|
||||
## Performance
|
||||
|
||||
Benchmarked on [SWE-bench Lite](https://huggingface.co/datasets/princeton-nlp/SWE-bench_Lite_bm25_27K) (real GitHub issues with ~27k tokens of BM25-retrieved repo context per problem).
|
||||
|
||||
### Claude Opus — 5 problems, trigger=10k
|
||||
|
||||
| Metric | Baseline | Compressed | Delta |
|
||||
|---|---|---|---|
|
||||
| File overlap | 1.000 | 1.000 | +0.000 |
|
||||
| Exact file match | 100% | 100% | +0.0% |
|
||||
| Hunk overlap | 0.582 | 0.361 | -0.221 |
|
||||
| Content similarity | 0.367 | 0.373 | +0.006 |
|
||||
| Avg prompt tokens | 30,828 | 6,890 | -77.7% |
|
||||
| Avg cost/problem | $0.488 | $0.136 | **-72.0%** |
|
||||
|
||||
**Key takeaways:**
|
||||
|
||||
- **File-level targeting is fully preserved** — the model edits the same files with or without compression.
|
||||
- **Content similarity matches baseline** — the actual lines changed are comparable.
|
||||
- **Hunk overlap drops modestly** (-0.221) — the model targets the right files but may edit slightly different line ranges with less surrounding context.
|
||||
- **72% cost savings** with 78% token reduction.
|
||||
|
||||
### Metrics explained
|
||||
|
||||
| Metric | What it measures |
|
||||
|---|---|
|
||||
| **File overlap** | Fraction of gold-patch files present in the generated patch |
|
||||
| **Exact file match** | Whether the generated patch touches exactly the same set of files |
|
||||
| **Hunk overlap** | Fraction of gold hunk line ranges covered by generated hunks |
|
||||
| **Content similarity** | Jaccard similarity of changed lines (added/removed) between gold and generated patches |
|
||||
|
||||
### Running the SWE-bench eval
|
||||
|
||||
```bash
|
||||
# 5-problem quick check
|
||||
python tests/eval_swe_bench.py --model claude-opus-4-20250514 --problems 5
|
||||
|
||||
# Custom trigger/target
|
||||
python tests/eval_swe_bench.py --model gpt-4o --problems 20 \
|
||||
--compression-trigger 15000 --compression-target 10000
|
||||
|
||||
# With embedding scoring
|
||||
python tests/eval_swe_bench.py --model gpt-4o --problems 10 \
|
||||
--embedding-model text-embedding-3-small
|
||||
```
|
||||
|
||||
### Running the HumanEval-style eval
|
||||
|
||||
```bash
|
||||
python scripts/eval_compression.py --model gpt-4o --problems 5
|
||||
```
|
||||
|
|
@ -9,6 +9,10 @@ import TabItem from '@theme/TabItem';
|
|||
import NavigationCards from '@site/src/components/NavigationCards';
|
||||
import Image from '@theme/IdealImage';
|
||||
|
||||
:::note Security Update
|
||||
The Trivy supply-chain compromise has been contained :tada: . All affected packages have been deleted and current releases are free of the compromised code/component. Please refer to our [Security Townhall](/blog/security-townhall-updates) for a deeper understanding of the problem, and [CI/CD v2](/blog/ci-cd-v2-improvements) for how we're improving moving forward.
|
||||
:::
|
||||
|
||||
<Image style={{padding: '10px', margin: '0 0 2.5rem'}} img={require('../img/hero.png')} />
|
||||
|
||||
**LiteLLM** is an open-source library that gives you a single, unified interface to call 100+ LLMs — OpenAI, Anthropic, Vertex AI, Bedrock, and more — using the OpenAI format.
|
||||
|
|
|
|||
|
|
@ -9,8 +9,8 @@ LiteLLM supports Google's Veo video generation models through a unified API inte
|
|||
|-------|-------|
|
||||
| Description | Google's Veo AI video generation models |
|
||||
| Provider Route on LiteLLM | `gemini/` |
|
||||
| Supported Models | `veo-3.0-generate-preview`, `veo-3.1-generate-preview` |
|
||||
| Cost Tracking | ✅ Duration-based pricing |
|
||||
| Supported Models | Veo 3.0 / 3.1 preview and production IDs (see table below), including **Veo 3.1 Lite** |
|
||||
| Cost Tracking | ✅ Duration-based pricing; optional **per-resolution** tiers where the catalog lists them (e.g. 720p vs 1080p) |
|
||||
| Logging Support | ✅ Full request/response logging |
|
||||
| Proxy Server Support | ✅ Full proxy integration with virtual keys |
|
||||
| Spend Management | ✅ Budget tracking and rate limiting |
|
||||
|
|
@ -79,6 +79,11 @@ print("Video downloaded successfully!")
|
|||
|------------|-------------|--------------|--------|
|
||||
| veo-3.0-generate-preview | Veo 3.0 video generation | 8 seconds | Preview |
|
||||
| veo-3.1-generate-preview | Veo 3.1 video generation | 8 seconds | Preview |
|
||||
| veo-3.1-lite-generate-preview | Veo 3.1 **Lite** (cost-efficient; [Gemini pricing](https://ai.google.dev/gemini-api/docs/video)) | Per Google docs | Preview |
|
||||
| veo-3.1-fast-generate-preview / `…-001` | Faster / prod variants | Per Google docs | Preview / GA |
|
||||
| veo-3.1-generate-001 | Veo 3.1 production | Per Google docs | GA |
|
||||
|
||||
Use the full LiteLLM model id with the `gemini/` prefix (for example `gemini/veo-3.1-lite-generate-preview`).
|
||||
|
||||
## Video Generation Parameters
|
||||
|
||||
|
|
@ -87,14 +92,29 @@ LiteLLM automatically maps OpenAI-style parameters to Veo's format:
|
|||
| OpenAI Parameter | Veo Parameter | Description | Example |
|
||||
|------------------|---------------|-------------|---------|
|
||||
| `prompt` | `prompt` | Text description of the video | "A cat playing" |
|
||||
| `size` | `aspectRatio` | Video dimensions → aspect ratio | "1280x720" → "16:9" |
|
||||
| `size` | `aspectRatio` and, when applicable, **`resolution`** | Standard widths/heights map to landscape/portrait **and** to `720p` or `1080p` for the API | See below |
|
||||
| `seconds` | `durationSeconds` | Duration in seconds | "8" → 8 |
|
||||
| `input_reference` | `image` | Reference image to animate | File object or path |
|
||||
| `model` | `model` | Model to use | "gemini/veo-3.0-generate-preview" |
|
||||
|
||||
### Size to Aspect Ratio Mapping
|
||||
### `size` and output resolution
|
||||
|
||||
When you pass a **standard `size`** string, LiteLLM sets both:
|
||||
|
||||
- **Aspect ratio** (`16:9` or `9:16`) — same as before.
|
||||
- **Output resolution** (`720p` or `1080p`) when the height is clear from the preset, so the correct Veo tier is requested without extra fields.
|
||||
|
||||
| `size` | Aspect ratio | Resolution sent to Veo |
|
||||
|--------|----------------|-------------------------|
|
||||
| `1280x720`, `720x1280` | `16:9` / `9:16` | `720p` |
|
||||
| `1920x1080`, `1080x1920` | `16:9` / `9:16` | `1080p` |
|
||||
|
||||
Other `size` values still map to an aspect ratio (defaulting to `16:9` when unknown); resolution is left to **Google’s default** unless you set it yourself.
|
||||
|
||||
You can also pass Veo’s **`resolution`** (for example via `extra_body`) if you need an explicit value that does not match the presets above. If you set `resolution` yourself, it takes precedence over the value inferred from `size`.
|
||||
|
||||
### Size to aspect ratio (reference)
|
||||
|
||||
LiteLLM automatically converts size dimensions to Veo's aspect ratio format:
|
||||
- `"1280x720"`, `"1920x1080"` → `"16:9"` (landscape)
|
||||
- `"720x1280"`, `"1080x1920"` → `"9:16"` (portrait)
|
||||
|
||||
|
|
@ -293,7 +313,14 @@ with open("video.mp4", "wb") as f:
|
|||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Cost Tracking
|
||||
## Cost tracking and spend
|
||||
|
||||
LiteLLM estimates **video spend** from:
|
||||
|
||||
1. **How long** the generated clip is billed for (seconds), and
|
||||
2. **The per-second price** for that model in LiteLLM’s model catalog (aligned with [Google’s Gemini API video pricing](https://ai.google.dev/gemini-api/docs/video) where applicable).
|
||||
|
||||
Some models charge **different per-second rates** for **720p** vs **1080p**. When you use the standard `size` presets above (or set `resolution` explicitly), LiteLLM uses the matching tier so **proxy spend, logs, and budgets** line up with the resolution you requested.
|
||||
|
||||
LiteLLM automatically tracks costs for Veo video generation:
|
||||
|
||||
|
|
@ -314,8 +341,8 @@ response = litellm.video_generation(
|
|||
| Feature | OpenAI (Sora) | Gemini (Veo) |
|
||||
|---------|---------------|--------------|
|
||||
| Reference Images | ✅ Supported | ❌ Not supported |
|
||||
| Size Control | ✅ Supported | ❌ Not supported |
|
||||
| Duration Control | ✅ Supported | ❌ Not supported |
|
||||
| Size / dimensions | ✅ Supported | ✅ Supported via `size` → aspect ratio + `720p`/`1080p` where preset |
|
||||
| Duration (`seconds`) | ✅ Supported | ✅ Supported (maps to `durationSeconds`; limits per Google docs) |
|
||||
| Video Remix/Edit | ✅ Supported | ❌ Not supported |
|
||||
| Video List | ✅ Supported | ❌ Not supported |
|
||||
| Prompt-based Generation | ✅ Supported | ✅ Supported |
|
||||
|
|
|
|||
|
|
@ -487,6 +487,7 @@ router_settings:
|
|||
| AZURE_STORAGE_CLIENT_ID | The Application Client ID to use for Authentication to Azure Blob Storage logging
|
||||
| AZURE_STORAGE_CLIENT_SECRET | The Application Client Secret to use for Authentication to Azure Blob Storage logging
|
||||
| AZURE_VECTOR_STORE_COST_PER_GB_PER_DAY | Cost per GB per day for Azure Vector Store service
|
||||
| BACKGROUND_HEALTH_CHECK_MAX_TOKENS | Optional global default for `max_tokens` on proxy background health checks when a model has no `health_check_max_tokens`. If unset, non-wildcard models default to 1. Applies to wildcard routes when set. Default is unset
|
||||
| BATCH_STATUS_POLL_INTERVAL_SECONDS | Interval in seconds for polling batch status. Default is 3600 (1 hour)
|
||||
| BATCH_STATUS_POLL_MAX_ATTEMPTS | Maximum number of attempts for polling batch status. Default is 24 (for 24 hours)
|
||||
| BEDROCK_MAX_POLICY_SIZE | Maximum size for Bedrock policy. Default is 75
|
||||
|
|
@ -804,6 +805,8 @@ router_settings:
|
|||
| LITELLM_ASSETS_PATH | Path to directory for UI assets and logos. Used when running with read-only filesystem (e.g., Kubernetes). Default is `/var/lib/litellm/assets` in Docker.
|
||||
| LITELLM_BLOG_POSTS_URL | Custom URL for fetching LiteLLM blog posts JSON. Default is the GitHub main branch URL
|
||||
| LITELLM_CLI_JWT_EXPIRATION_HOURS | Expiration time in hours for CLI-generated JWT tokens. Default is 24 hours
|
||||
| LITELLM_CORS_ALLOW_CREDENTIALS | Set to `true` to explicitly allow credentials in CORS responses. When not set, credentials are disabled automatically if `LITELLM_CORS_ORIGINS` is `*` (wildcard) to prevent the browser security misconfiguration of reflecting any origin with credentials
|
||||
| LITELLM_CORS_ORIGINS | Comma-separated list of allowed CORS origins (e.g. `https://app.example.com,https://admin.example.com`). Defaults to `*` (all origins) when not set
|
||||
| LITELLM_DD_AGENT_HOST | Hostname or IP of DataDog agent for LiteLLM-specific logging. When set, logs are sent to agent instead of direct API
|
||||
| LITELLM_DEPLOYMENT_ENVIRONMENT | Environment name for the deployment (e.g., "production", "staging"). Used as a fallback when OTEL_ENVIRONMENT_NAME is not set. Sets the `environment` tag in telemetry data
|
||||
| LITELLM_DETAILED_TIMING | When true, adds detailed per-phase timing headers to responses (`x-litellm-timing-{pre-processing,llm-api,post-processing,message-copy}-ms`). Default is false. See [latency overhead docs](../troubleshoot/latency_overhead.md)
|
||||
|
|
@ -914,6 +917,7 @@ router_settings:
|
|||
| MODEL_COST_MAP_MAX_SHRINK_RATIO | Maximum allowed shrinkage ratio when validating a fetched model cost map against the local backup. Rejects the fetched map if it is smaller than this fraction of the backup. Default is 0.5
|
||||
| MODEL_COST_MAP_MIN_MODEL_COUNT | Minimum number of models a fetched cost map must contain to be considered valid. Default is 50
|
||||
| NO_DOCS | Flag to disable Swagger UI documentation
|
||||
| NO_OPENAPI | Flag to disable the /openapi.json endpoint
|
||||
| NO_REDOC | Flag to disable Redoc documentation
|
||||
| NO_PROXY | List of addresses to bypass proxy
|
||||
| NON_LLM_CONNECTION_TIMEOUT | Timeout in seconds for non-LLM service connections. Default is 15
|
||||
|
|
@ -924,6 +928,7 @@ router_settings:
|
|||
| OPENAI_CHATGPT_API_BASE | Alternative to CHATGPT_API_BASE. Base URL for ChatGPT API
|
||||
| OPENAI_FILE_SEARCH_COST_PER_1K_CALLS | Cost per 1000 calls for OpenAI file search. Default is 0.0025
|
||||
| OPENAI_ORGANIZATION | Organization identifier for OpenAI
|
||||
| OPENAPI_URL | The path to the OpenAPI JSON endpoint. **By default this is "/openapi.json"**
|
||||
| OPENID_BASE_URL | Base URL for OpenID Connect services
|
||||
| OPENID_CLIENT_ID | Client ID for OpenID Connect authentication
|
||||
| OPENID_CLIENT_SECRET | Client secret for OpenID Connect authentication
|
||||
|
|
|
|||
|
|
@ -14,6 +14,10 @@ Provider-specific cost tracking (e.g., [Vertex AI PayGo / priority pricing](../p
|
|||
[Sync model pricing data from GitHub](./sync_models_github.md) to ensure accurate cost tracking.
|
||||
:::
|
||||
|
||||
:::info Cost does not match your provider bill?
|
||||
Use the step-by-step workflow in [Debugging a cost discrepancy](../troubleshoot/cost_discrepancy): align time ranges, compare token categories (including cache), then decide whether the gap is ingestion, formula, or model-map pricing.
|
||||
:::
|
||||
|
||||
### How to Track Spend with LiteLLM
|
||||
|
||||
**Step 1**
|
||||
|
|
|
|||
|
|
@ -174,6 +174,7 @@ guardrails:
|
|||
- **`default_on`**: Automatically attach the guardrail to every request unless the client opts out.
|
||||
- **`hl-project-id` header**: Routes scans to a specific HiddenLayer project.
|
||||
- **`hl-requester-id` header**: Sets `metadata.requester_id` for auditing.
|
||||
- **`hl-session-id` header**: Groups related requests into a session for contextual analysis and tracing in the HiddenLayer console.
|
||||
|
||||
## Environment variables
|
||||
|
||||
|
|
|
|||
|
|
@ -71,11 +71,105 @@ For each step you choose an action for **pass**, **fail**, and optionally **erro
|
|||
3. Select **Flow Builder** (instead of the simple form)
|
||||
4. Design your flow:
|
||||
- **Trigger** — Incoming LLM request (runs when the policy matches)
|
||||
- **Steps** — Add guardrails, set **ON PASS**, **ON FAIL**, and **ON ERROR** actions per step (ON ERROR is optional; when unset, errors follow ON FAIL)
|
||||
- **End** — Request proceeds to the LLM
|
||||
5. Use the **+** between steps to insert new steps
|
||||
6. Use the **Test** panel to run sample messages through the pipeline before saving
|
||||
7. Click **Save** to create or update the policy
|
||||
- **Steps** — Add guardrails; set **ON PASS**, **ON FAIL**, and **ON API FAILURE** / **ON ERROR** per step (when **ON API FAILURE** is unset, technical errors follow **ON FAIL**)
|
||||
- **End** — Request proceeds to the LLM when the pipeline allows it
|
||||
5. Use **+** between steps to insert another guardrail step (for fallbacks, retries, or stricter second checks)
|
||||
6. Use **Test Pipeline** to run sample messages before saving
|
||||
7. Click **Save Policy** (or **Save**) to create or update the policy
|
||||
|
||||
### Configure guardrail fallbacks in the UI (walkthrough)
|
||||
|
||||
1. Click **Policies**
|
||||
|
||||
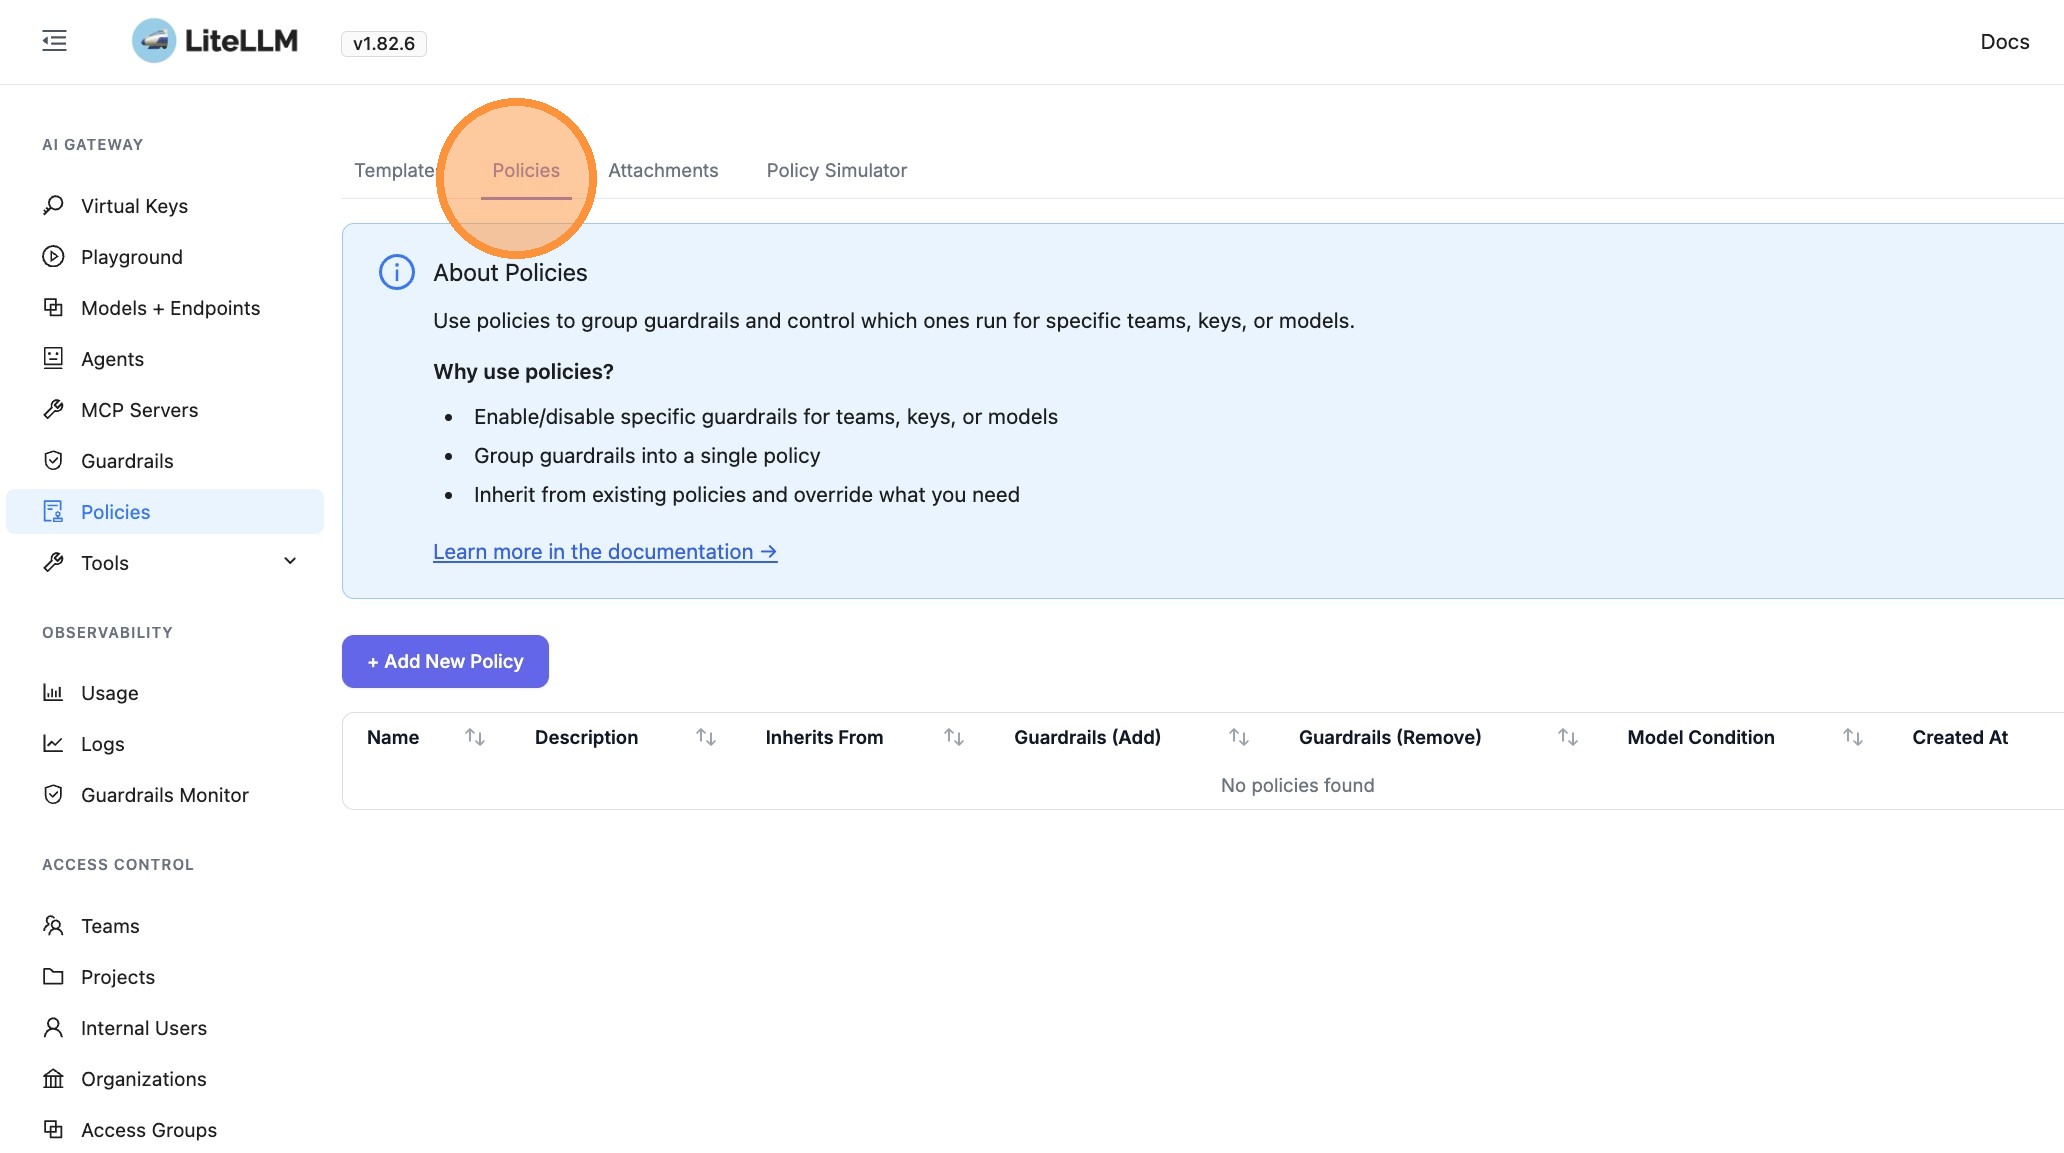
|
||||
|
||||
2. Click **+ Add New Policy**
|
||||
|
||||
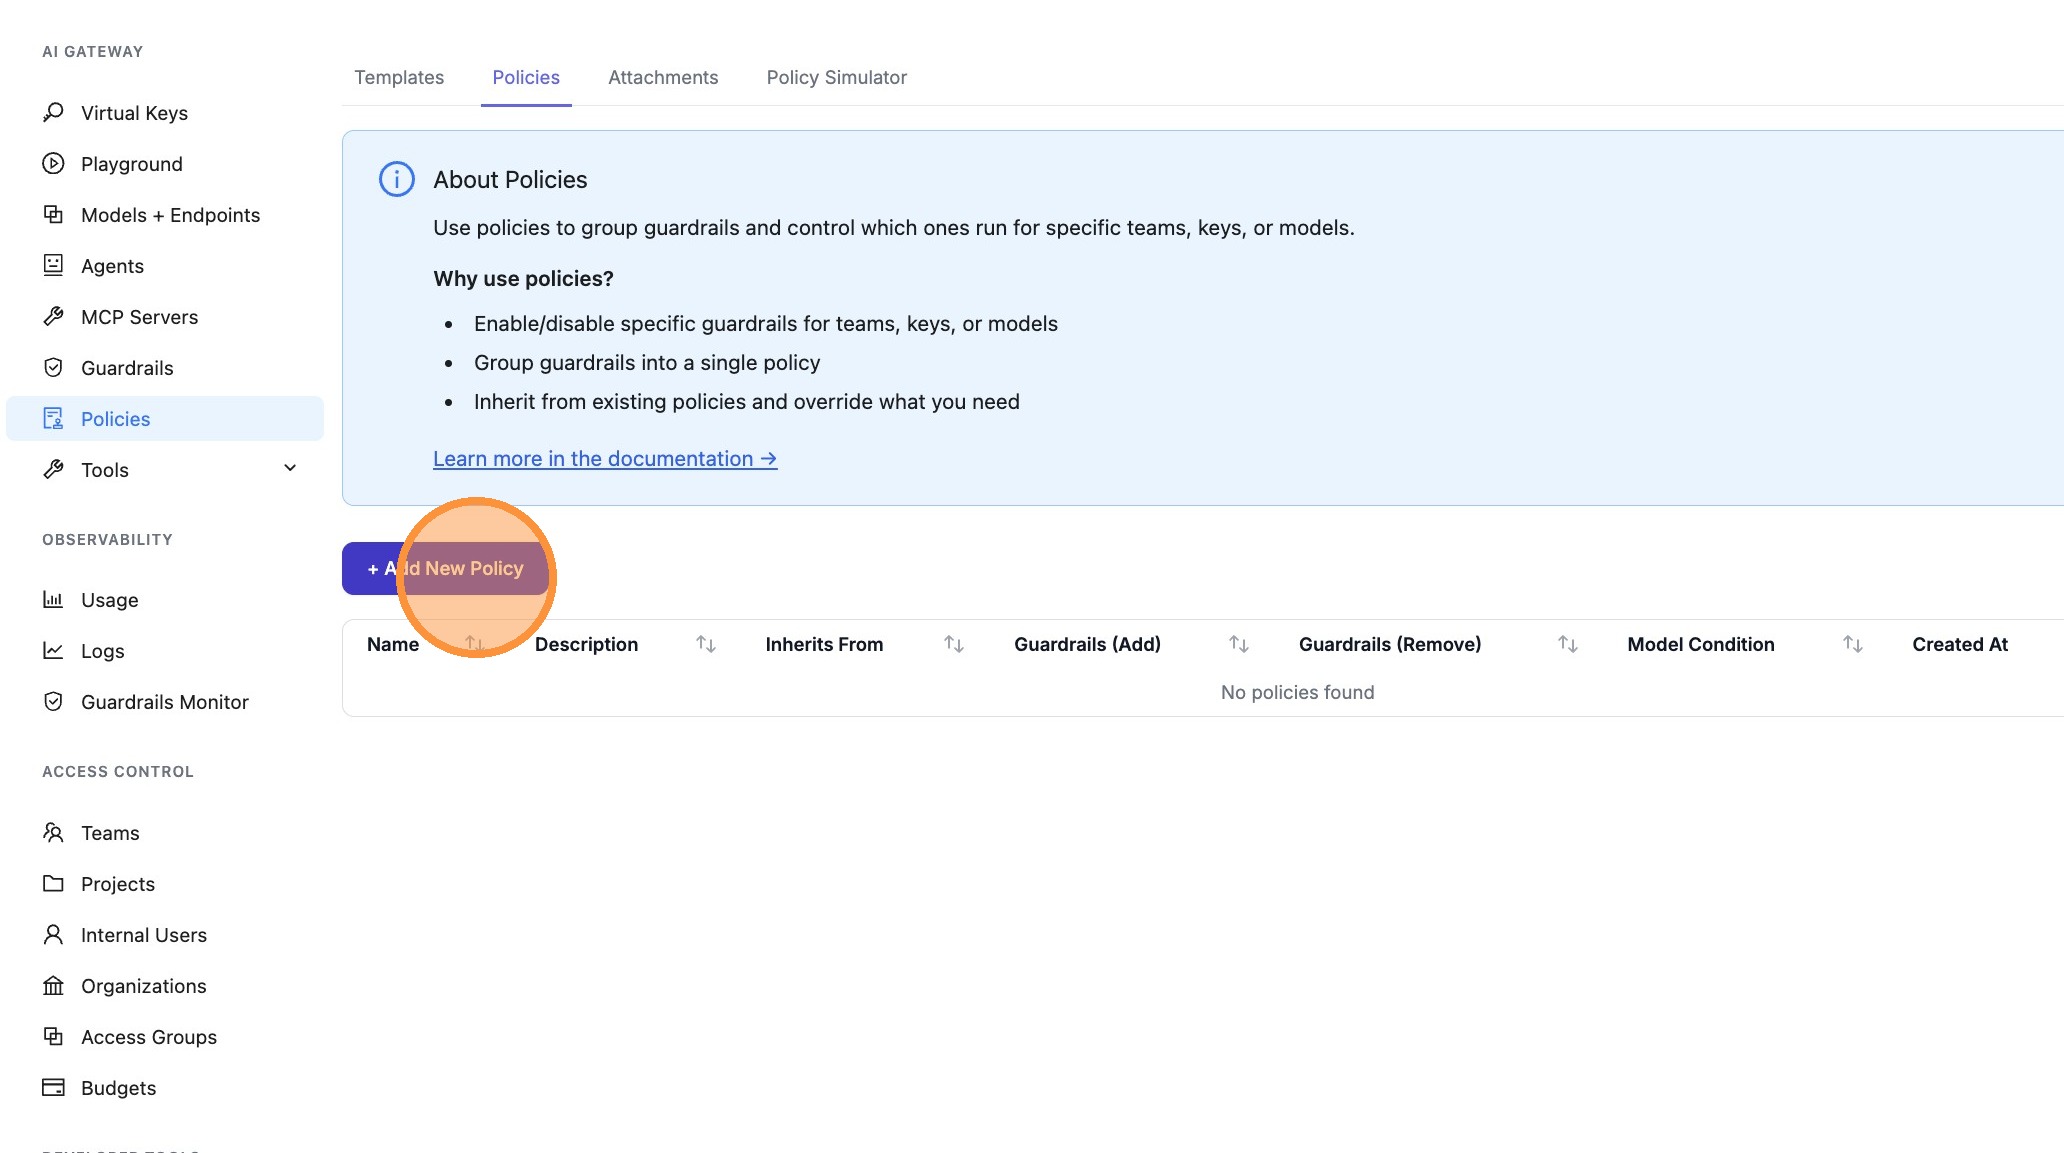
|
||||
|
||||
3. Click **Flow Builder**
|
||||
|
||||
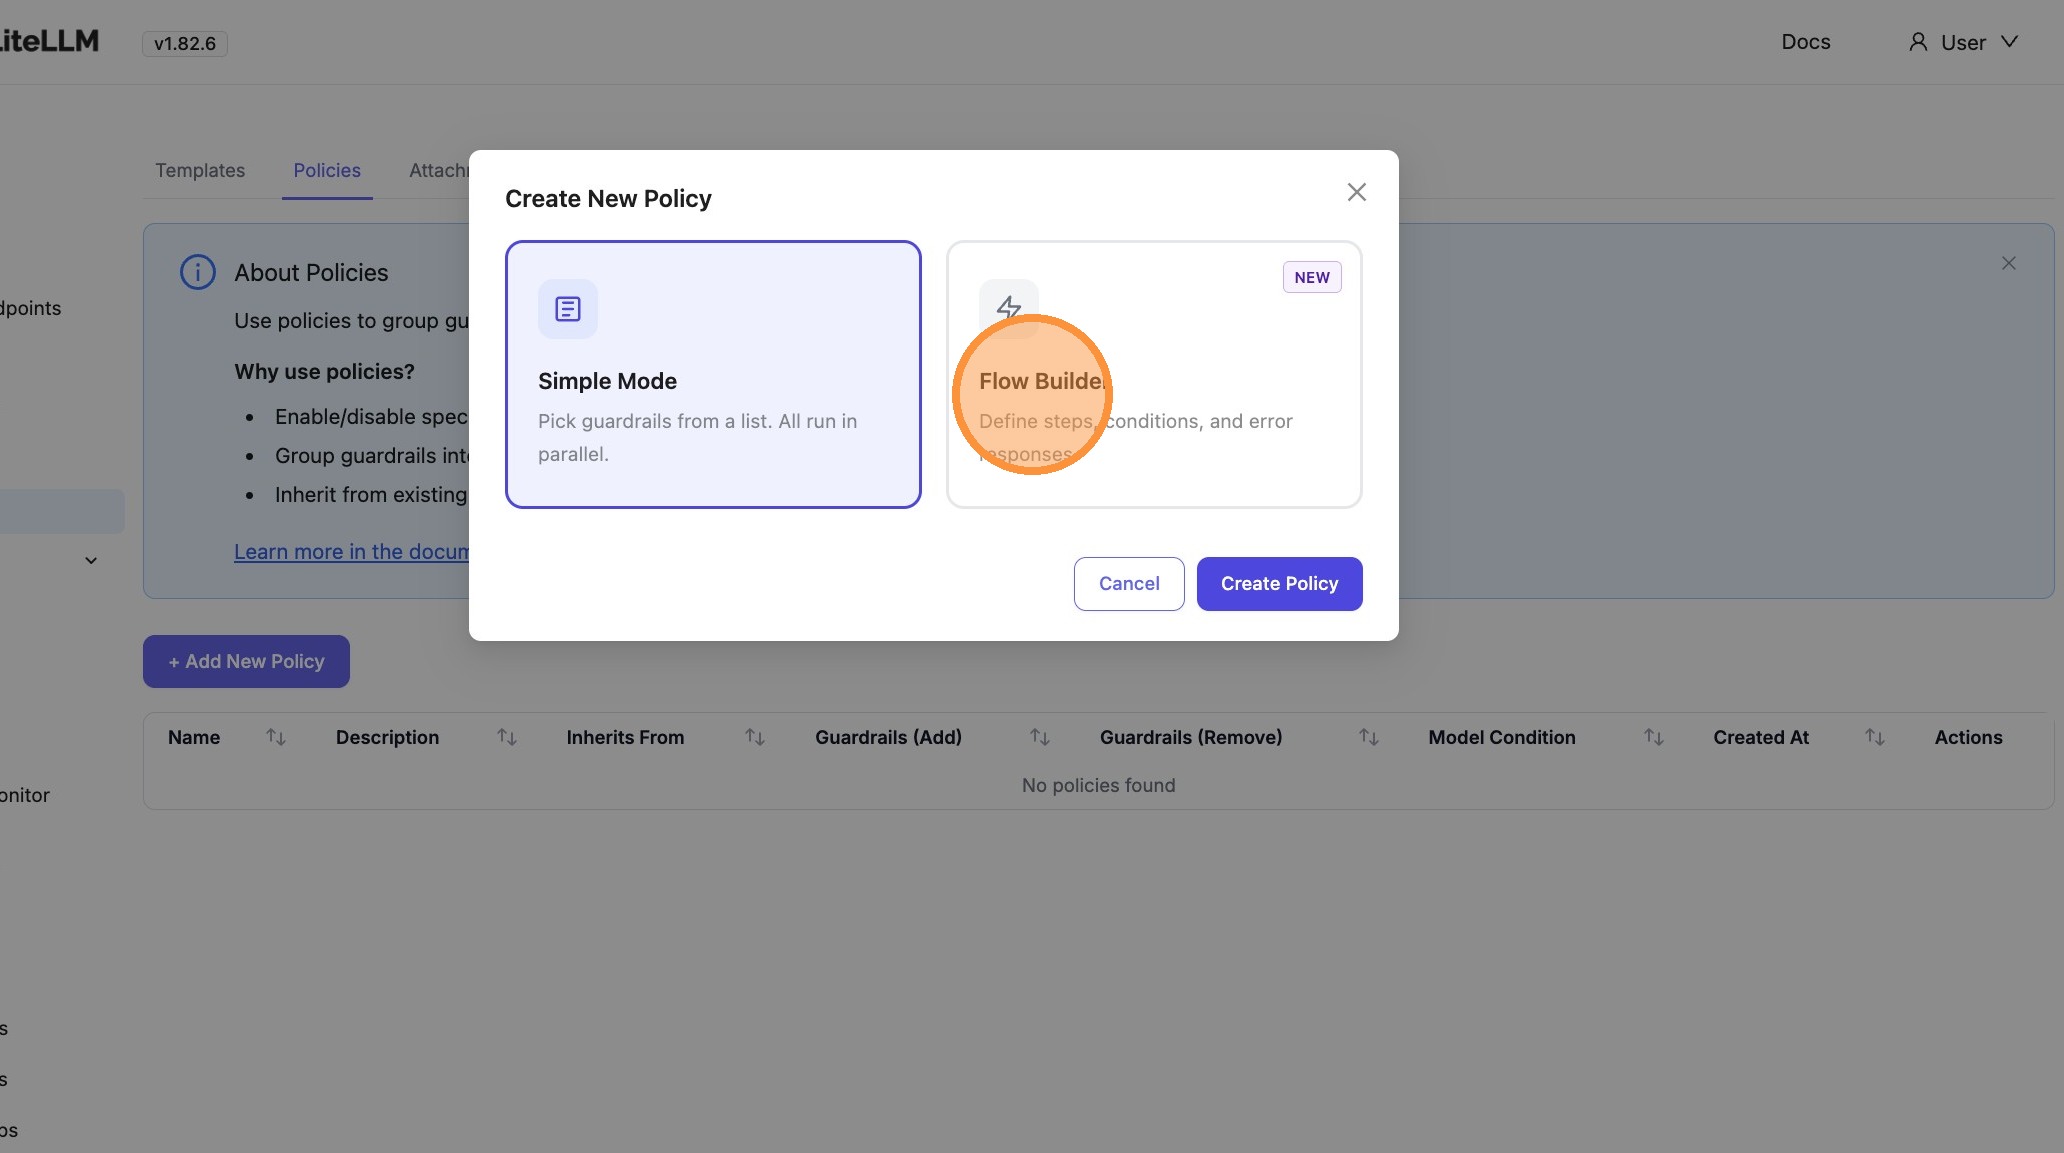
|
||||
|
||||
4. Click **Continue to Builder**
|
||||
|
||||
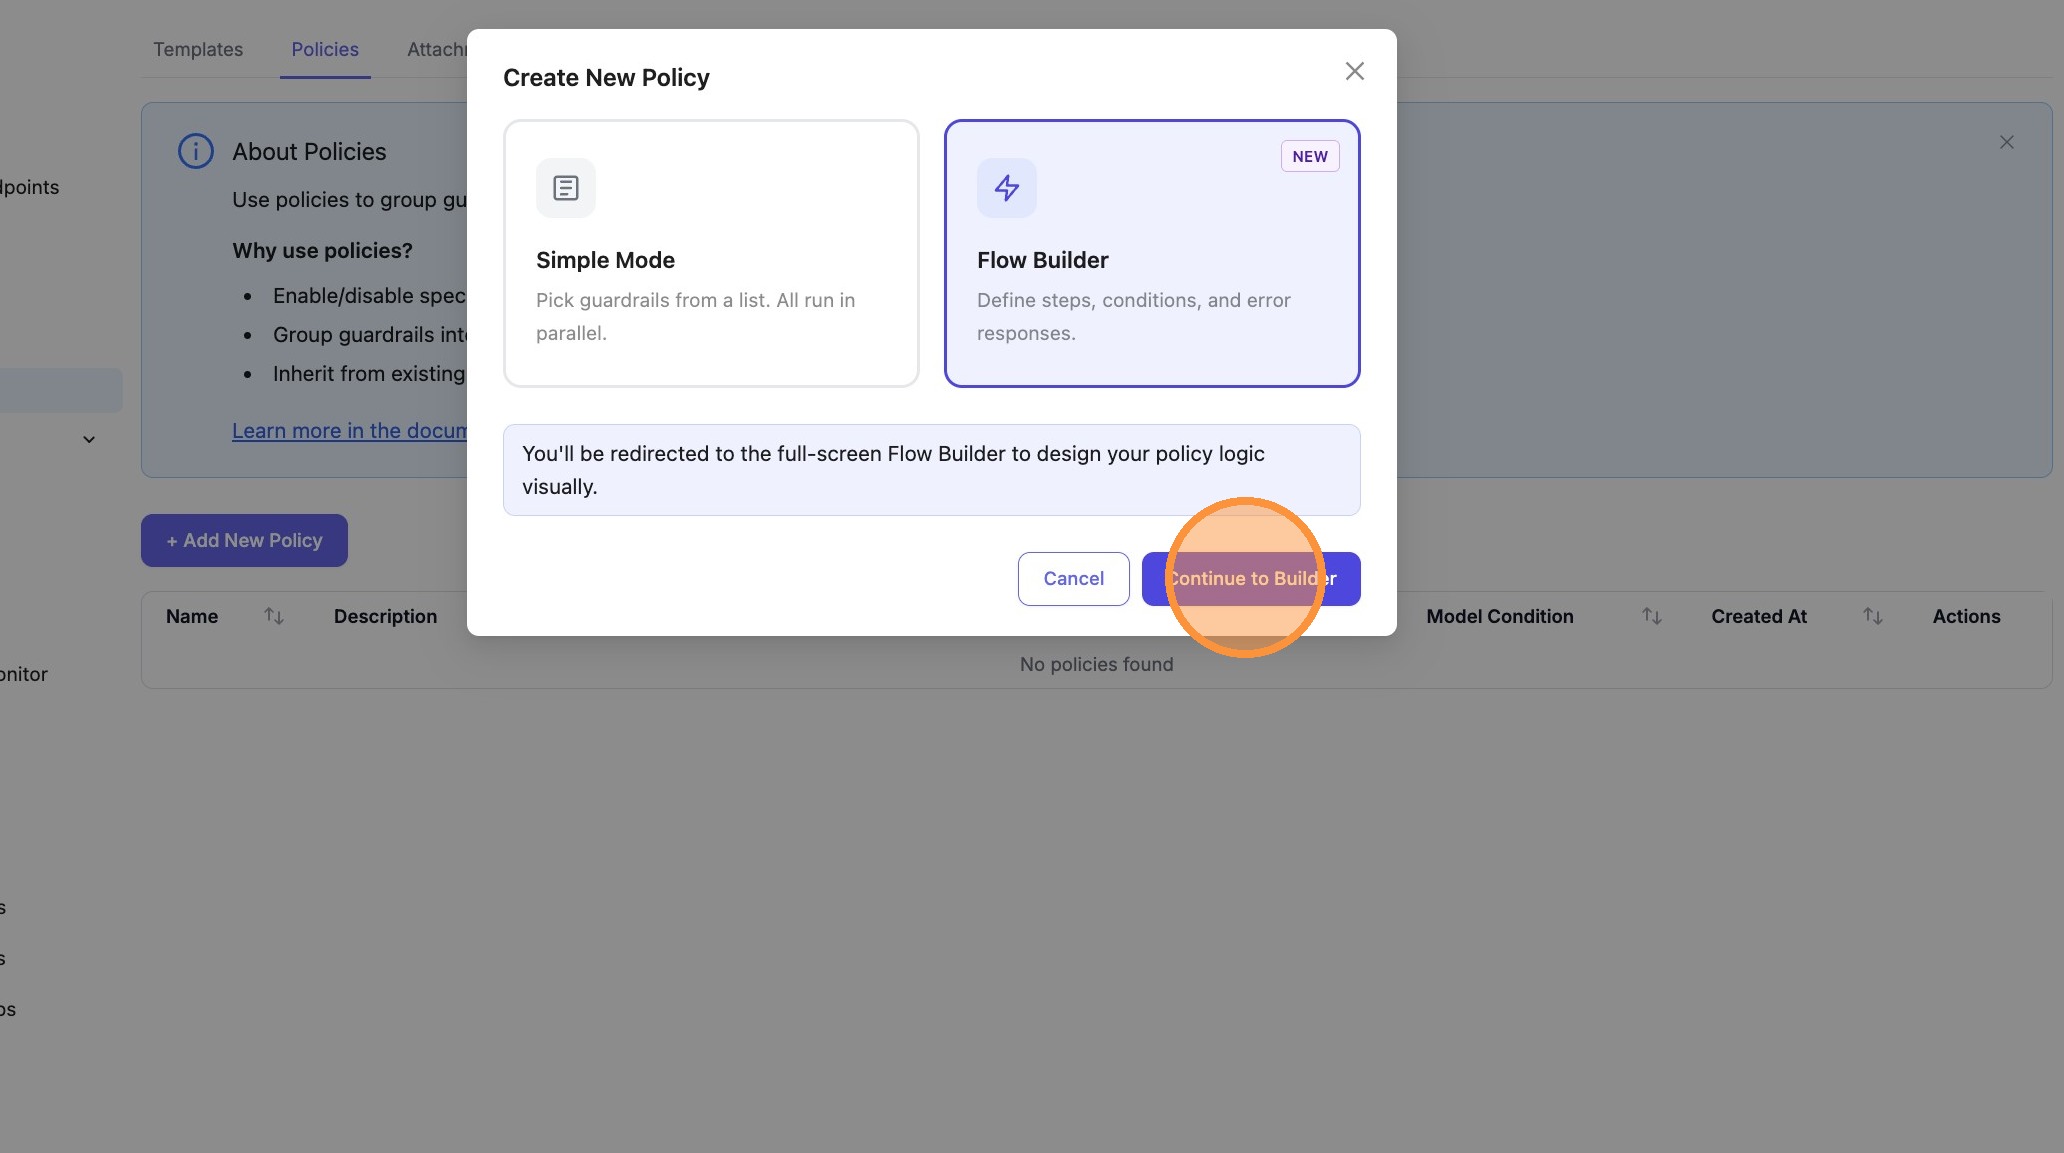
|
||||
|
||||
5. Click the **guardrail search** field on the first step
|
||||
|
||||
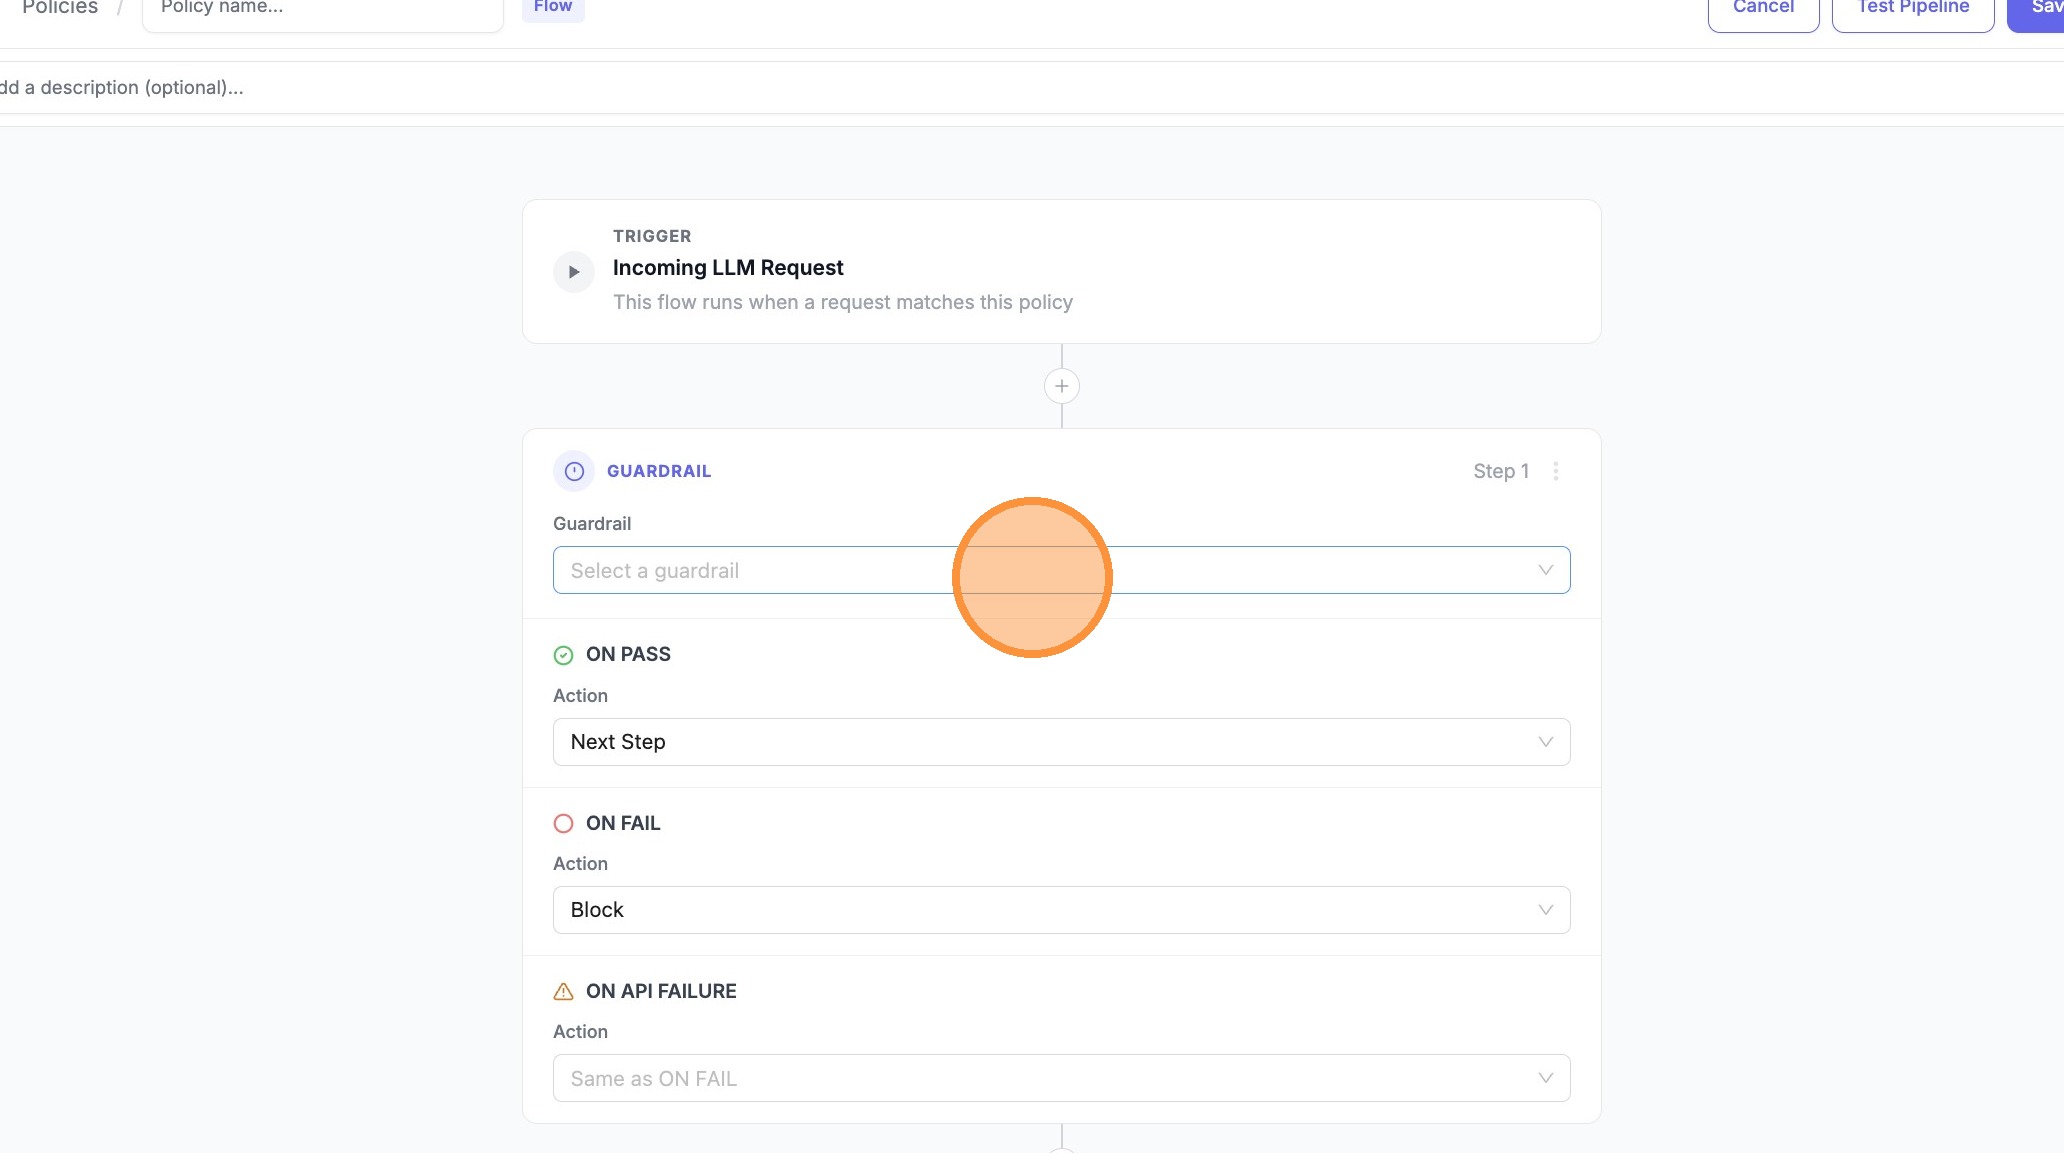
|
||||
|
||||
6. Choose **Test Moderation** (or your primary guardrail)
|
||||
|
||||
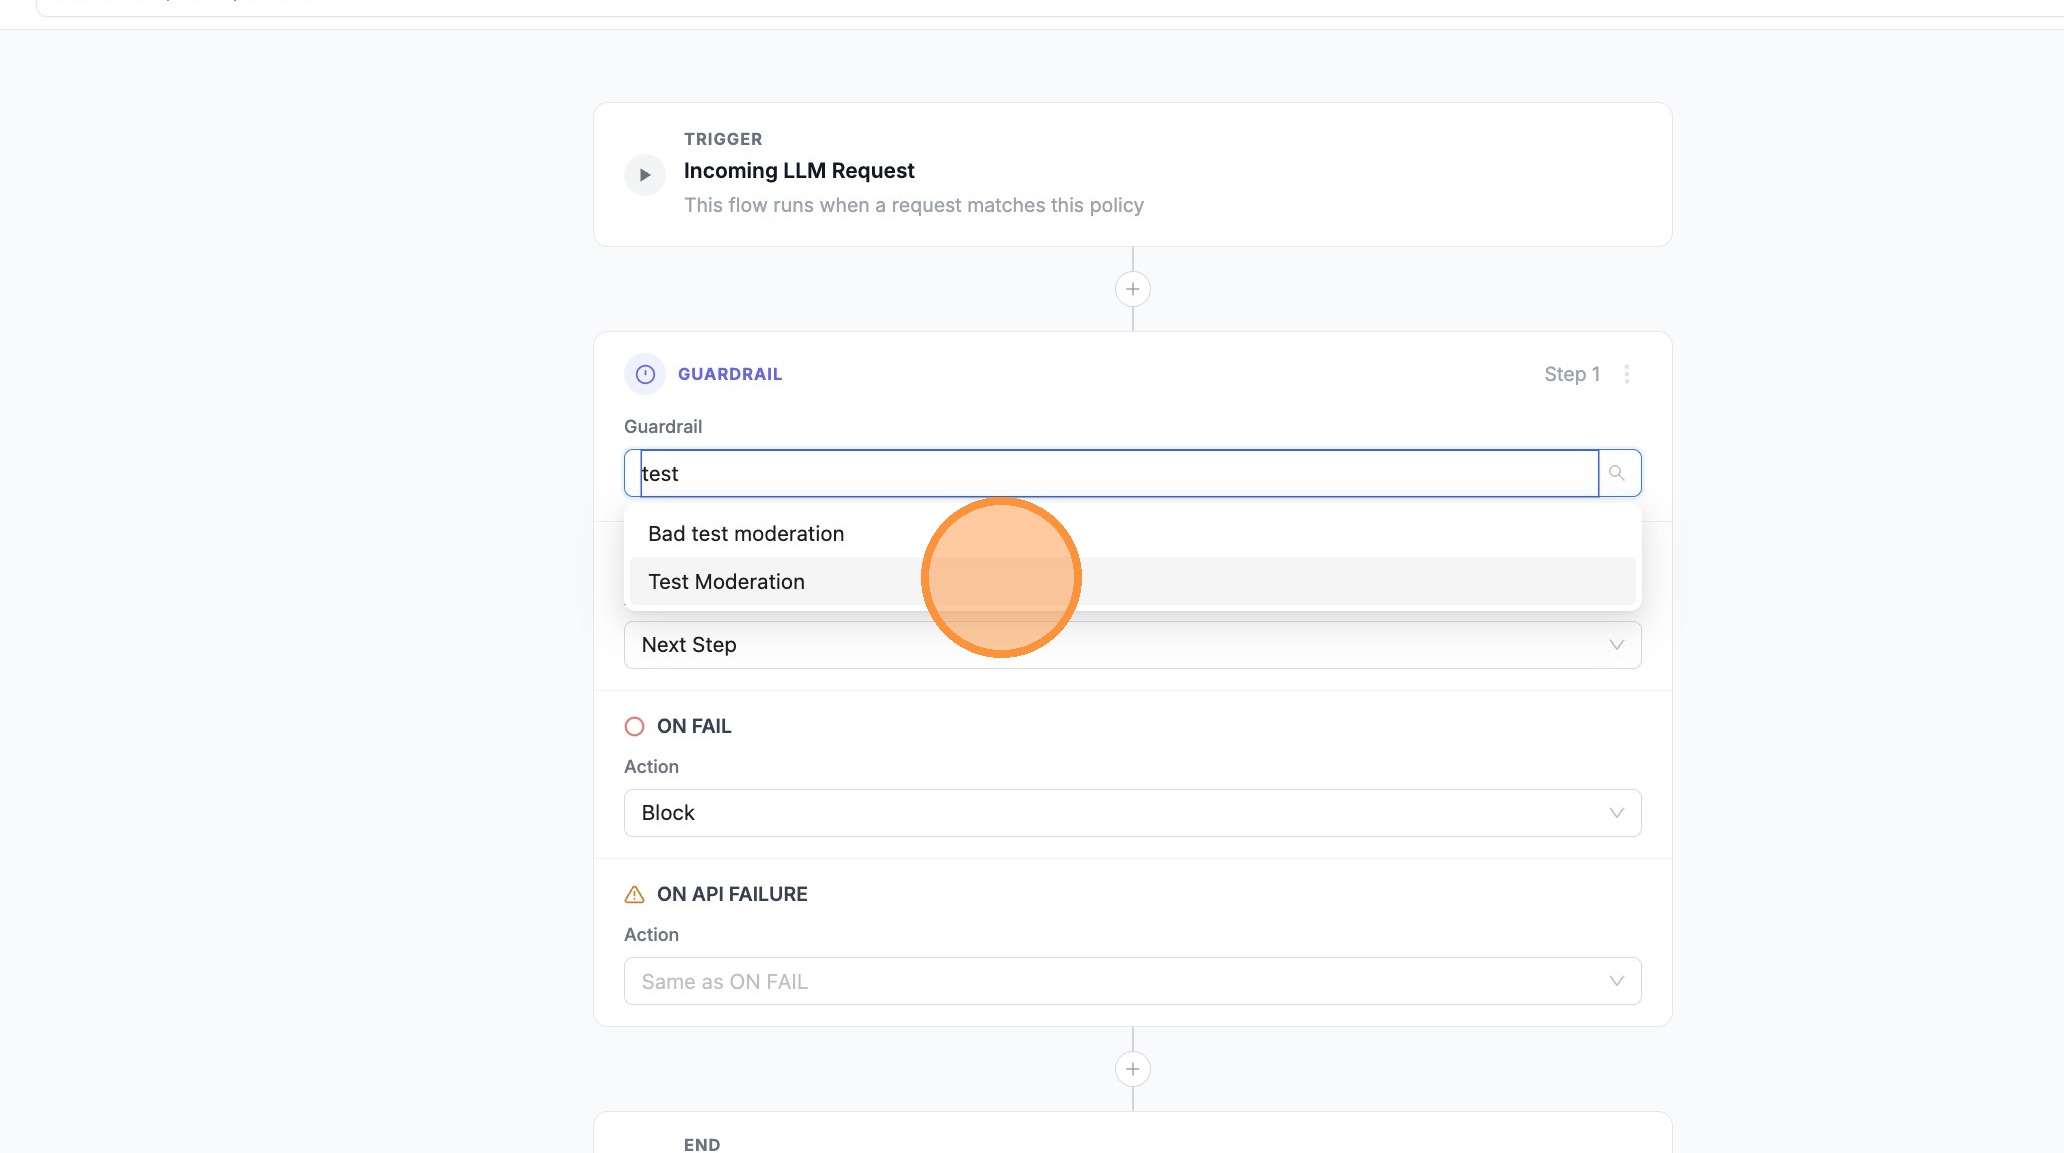
|
||||
|
||||
7. For one branch (e.g. **ON API FAILURE**), set the action to **Next Step** so the pipeline can fall through to the next guardrail when the API errors
|
||||
|
||||
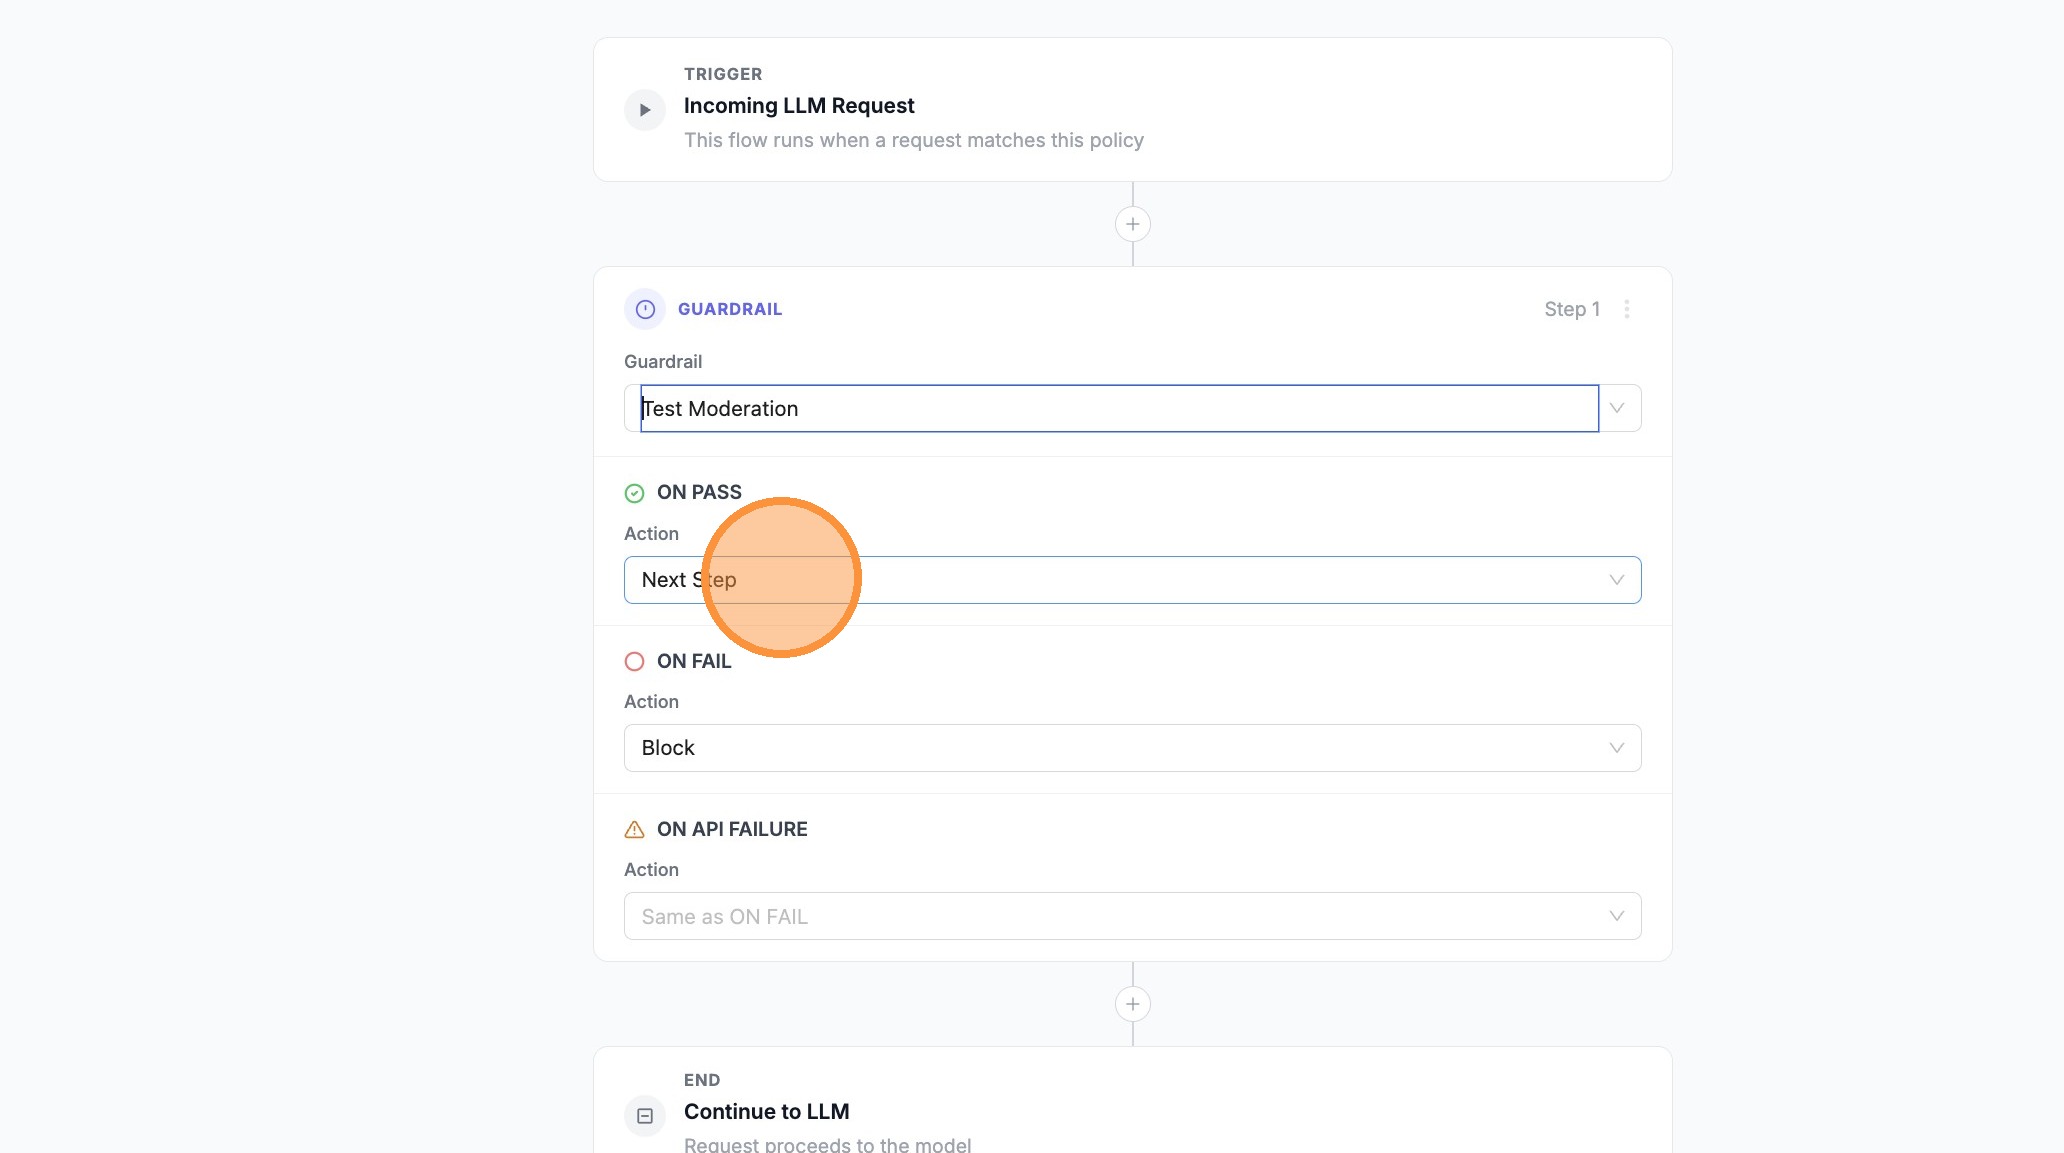
|
||||
|
||||
8. For **ON PASS**, set **Allow** (or **Next Step** if you need more steps before allowing)
|
||||
|
||||
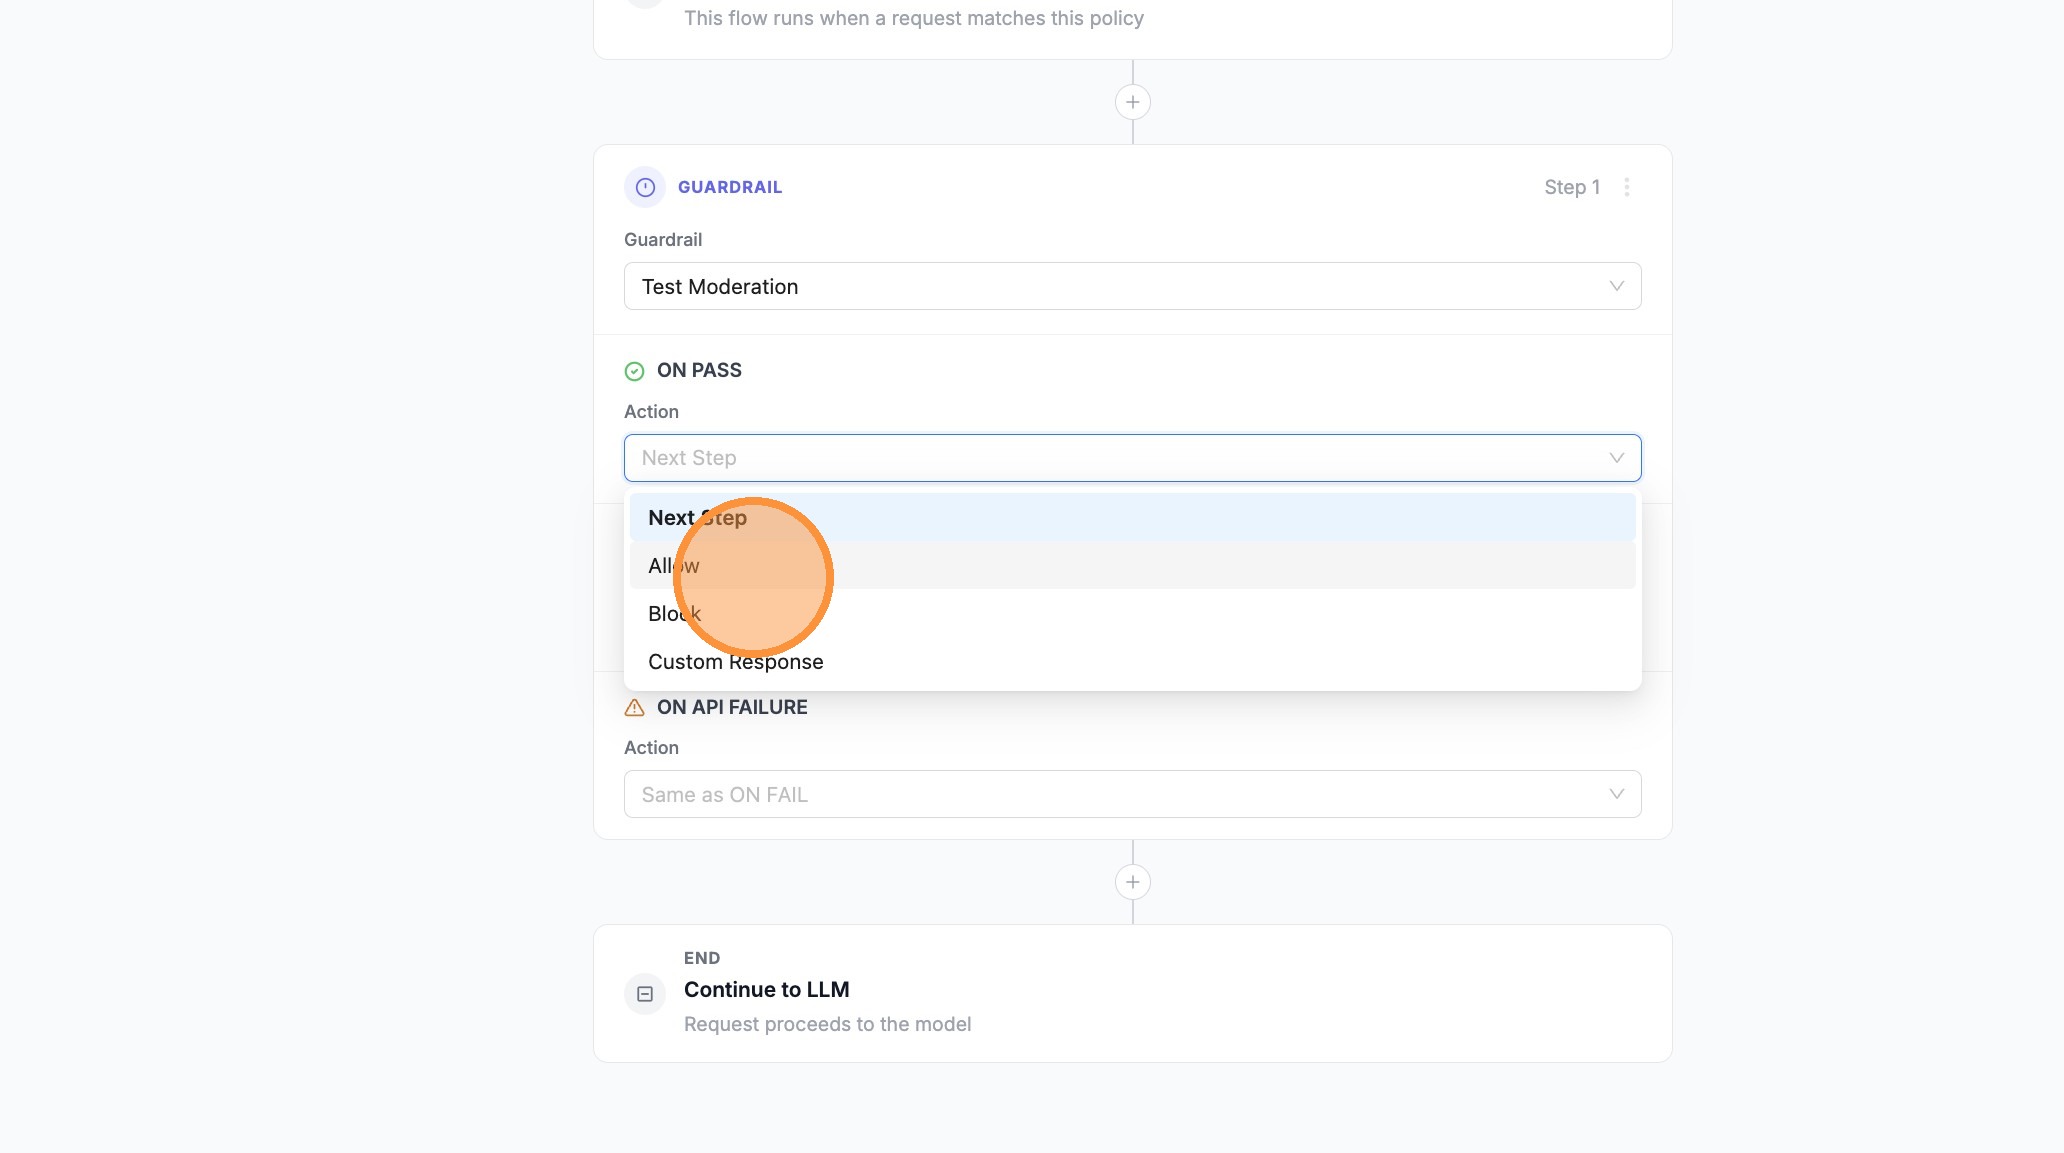
|
||||
|
||||
9. Open the next outcome’s search/dropdown (e.g. **ON FAIL**)
|
||||
|
||||
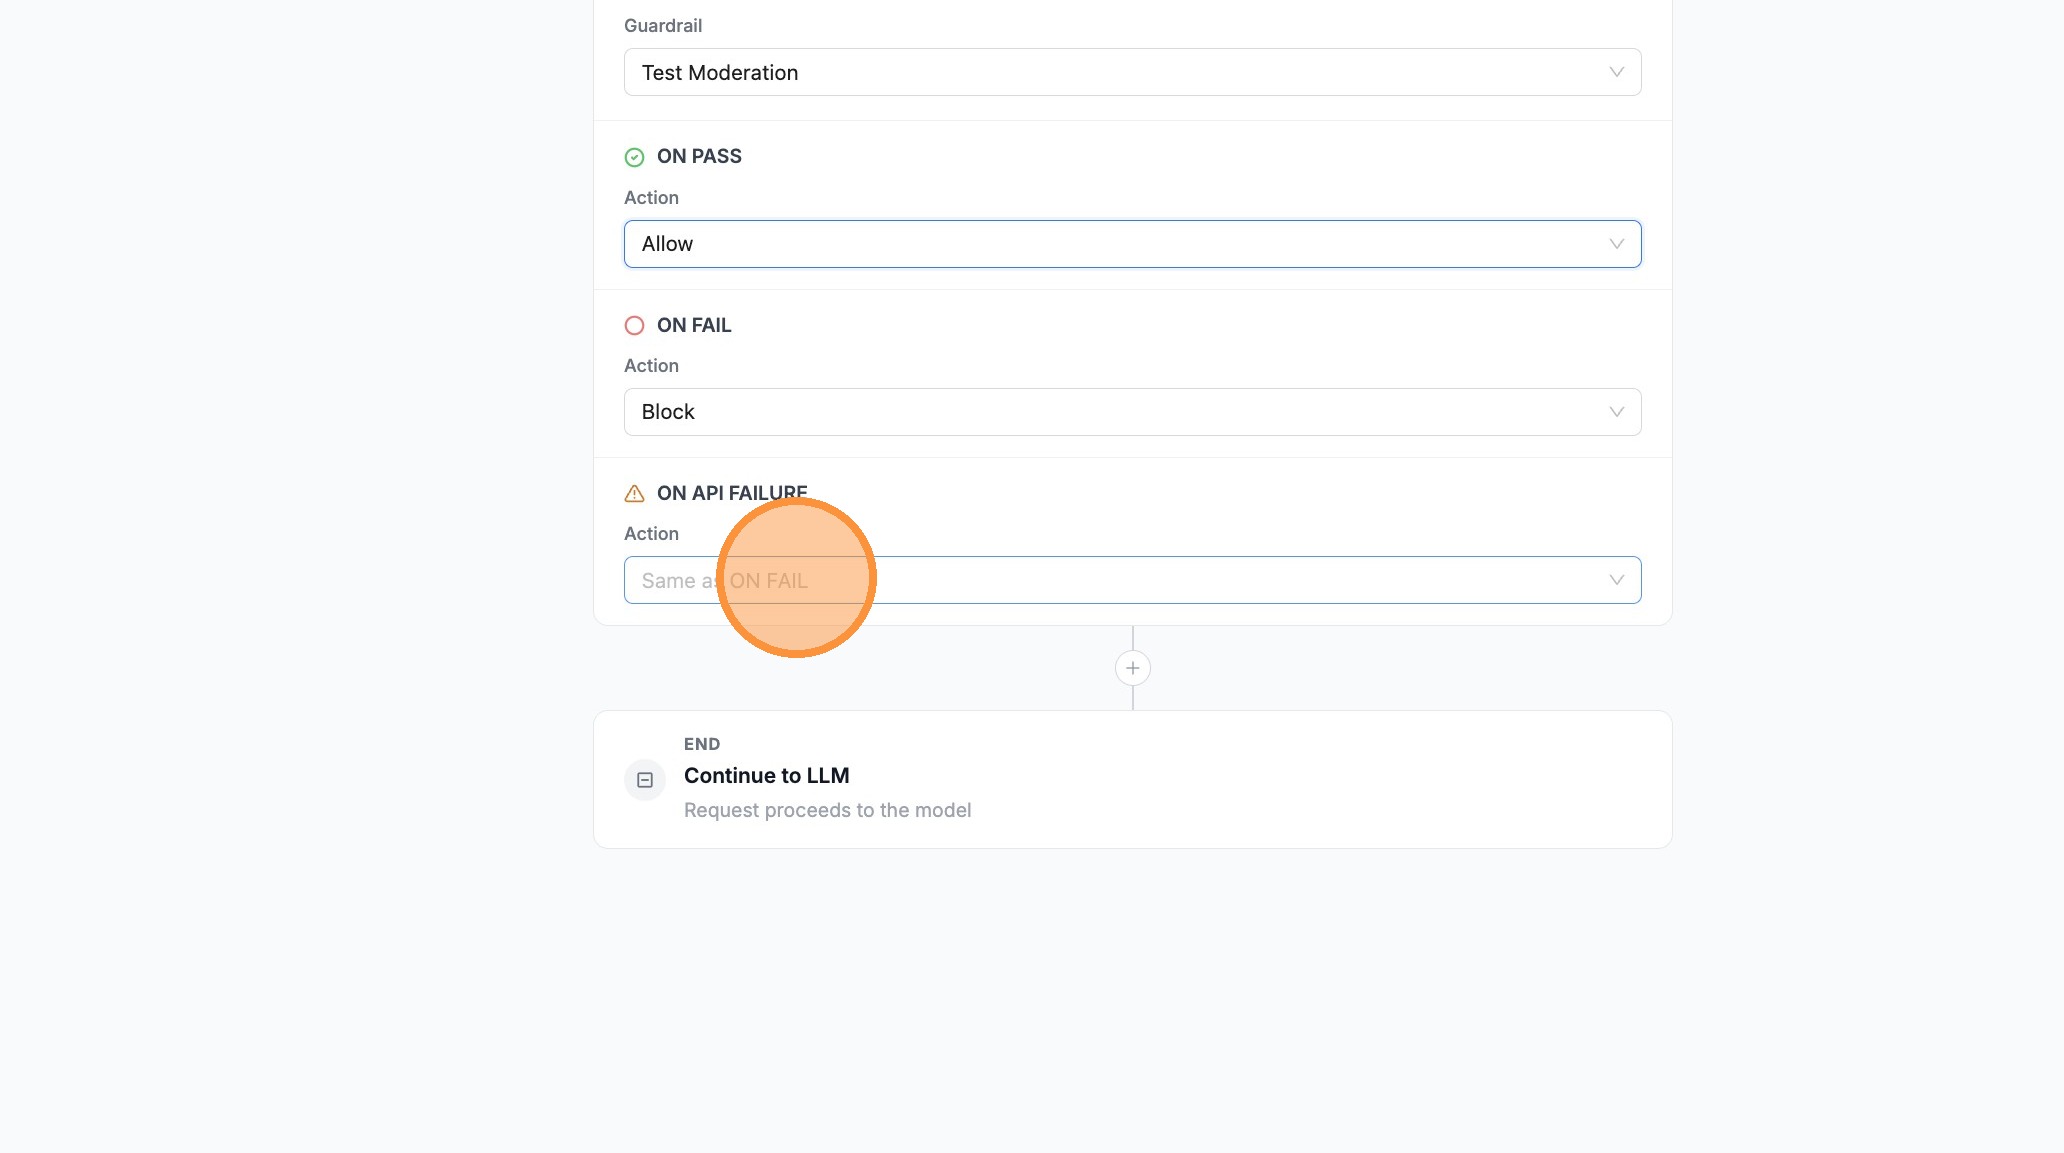
|
||||
|
||||
10. Set that branch to **Next Step** if failed checks should continue to your backup guardrail
|
||||
|
||||
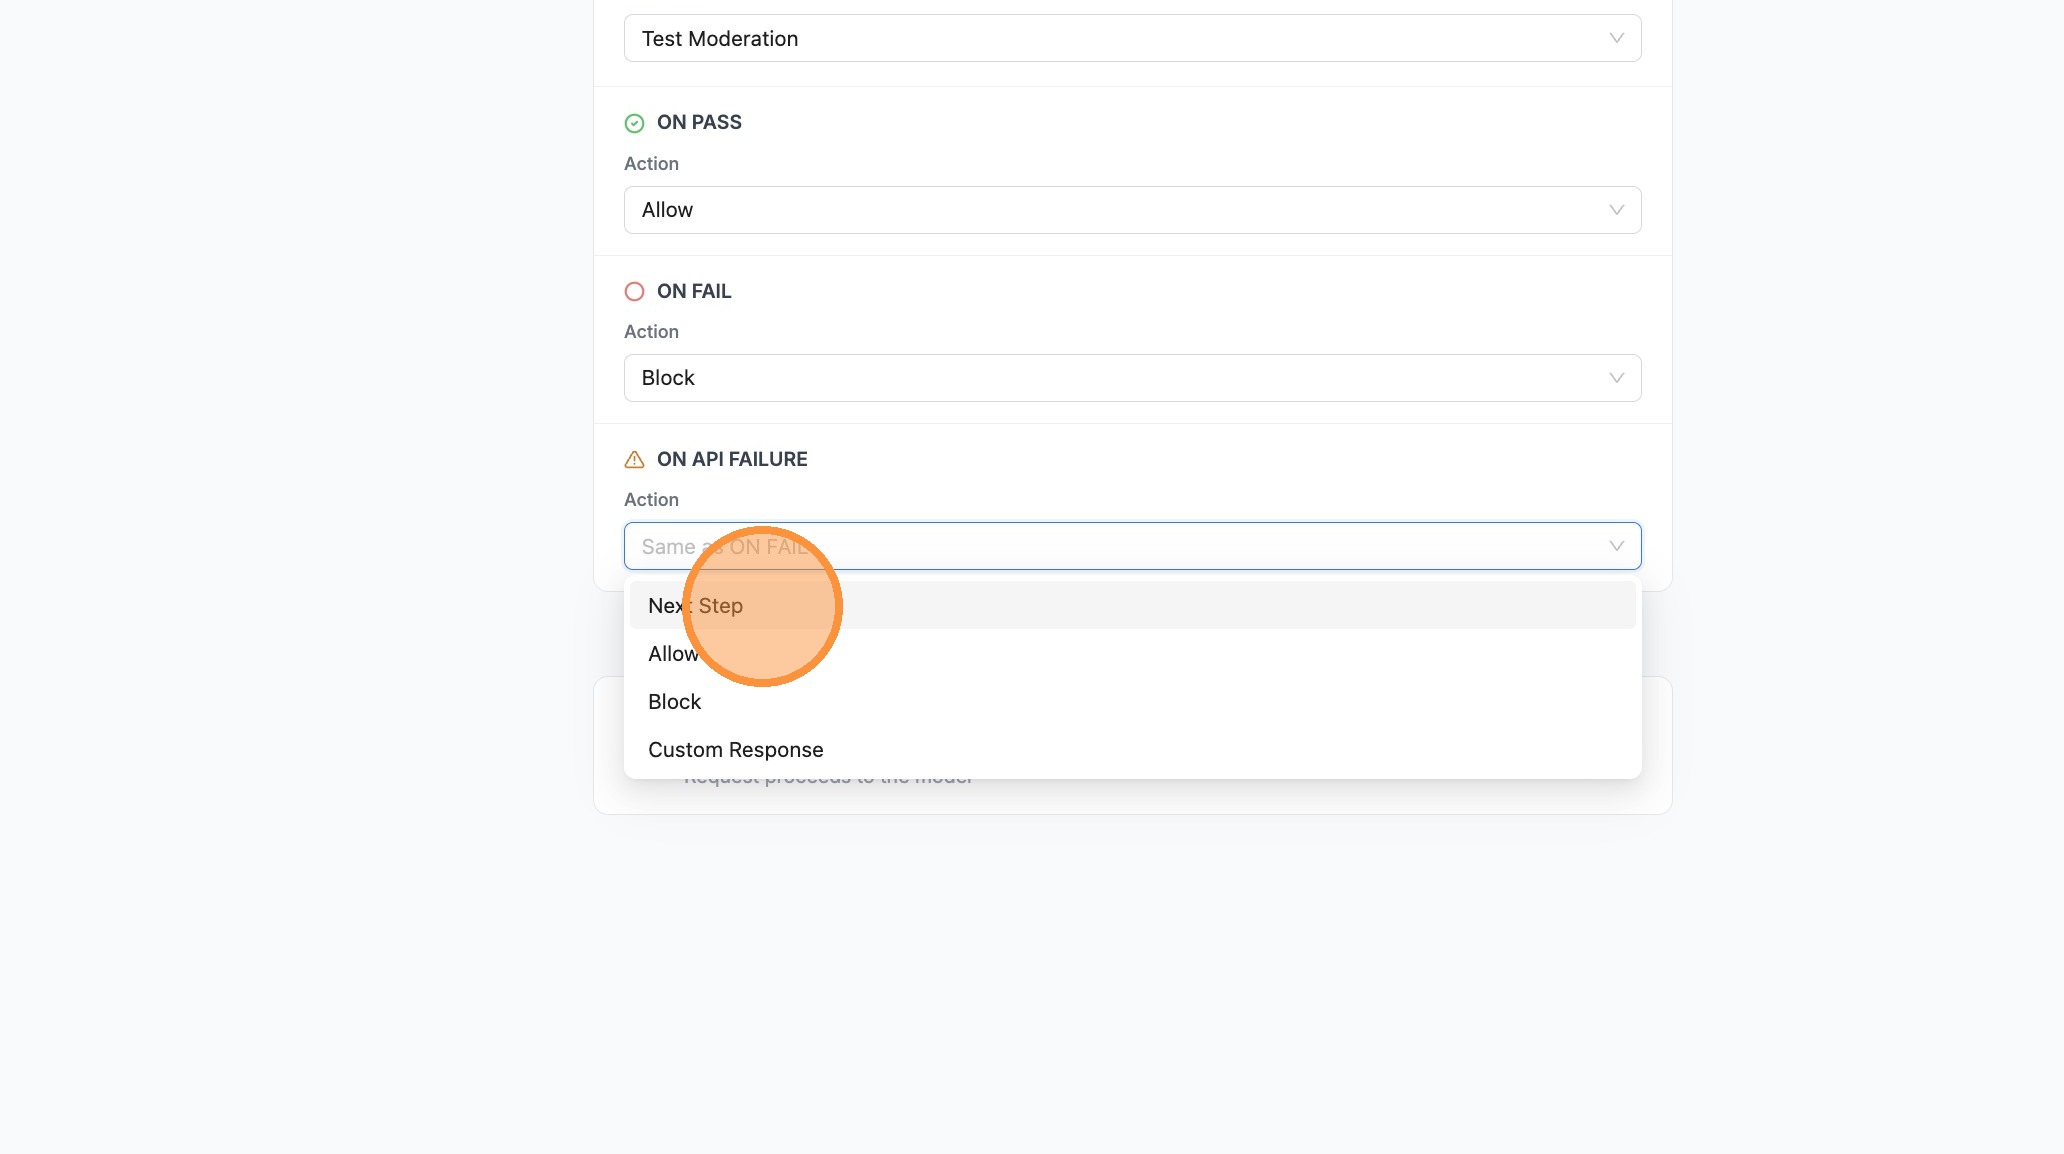
|
||||
|
||||
11. Click **+** between steps to add a second guardrail
|
||||
|
||||
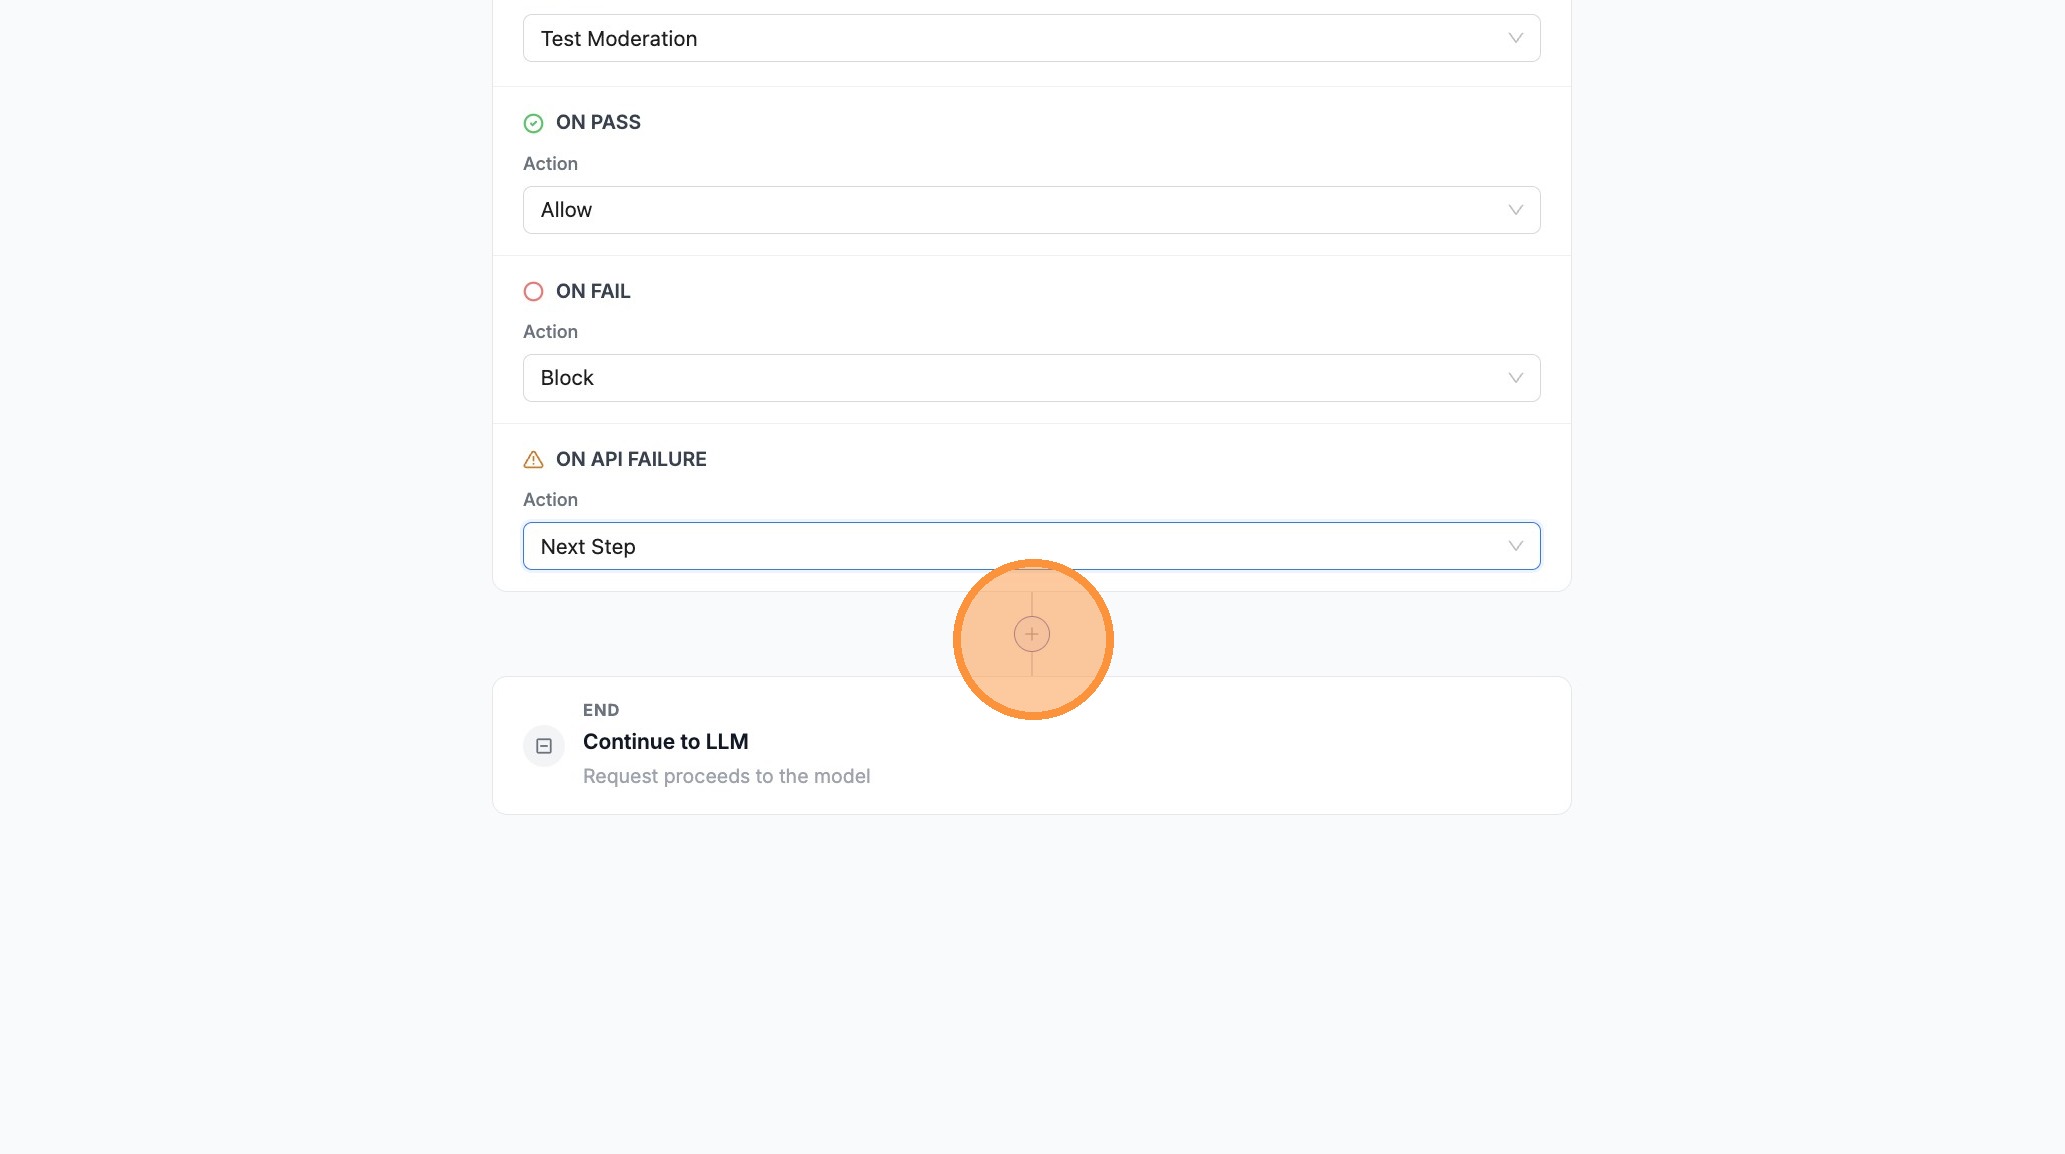
|
||||
|
||||
12. Open the guardrail search field on the new step
|
||||
|
||||
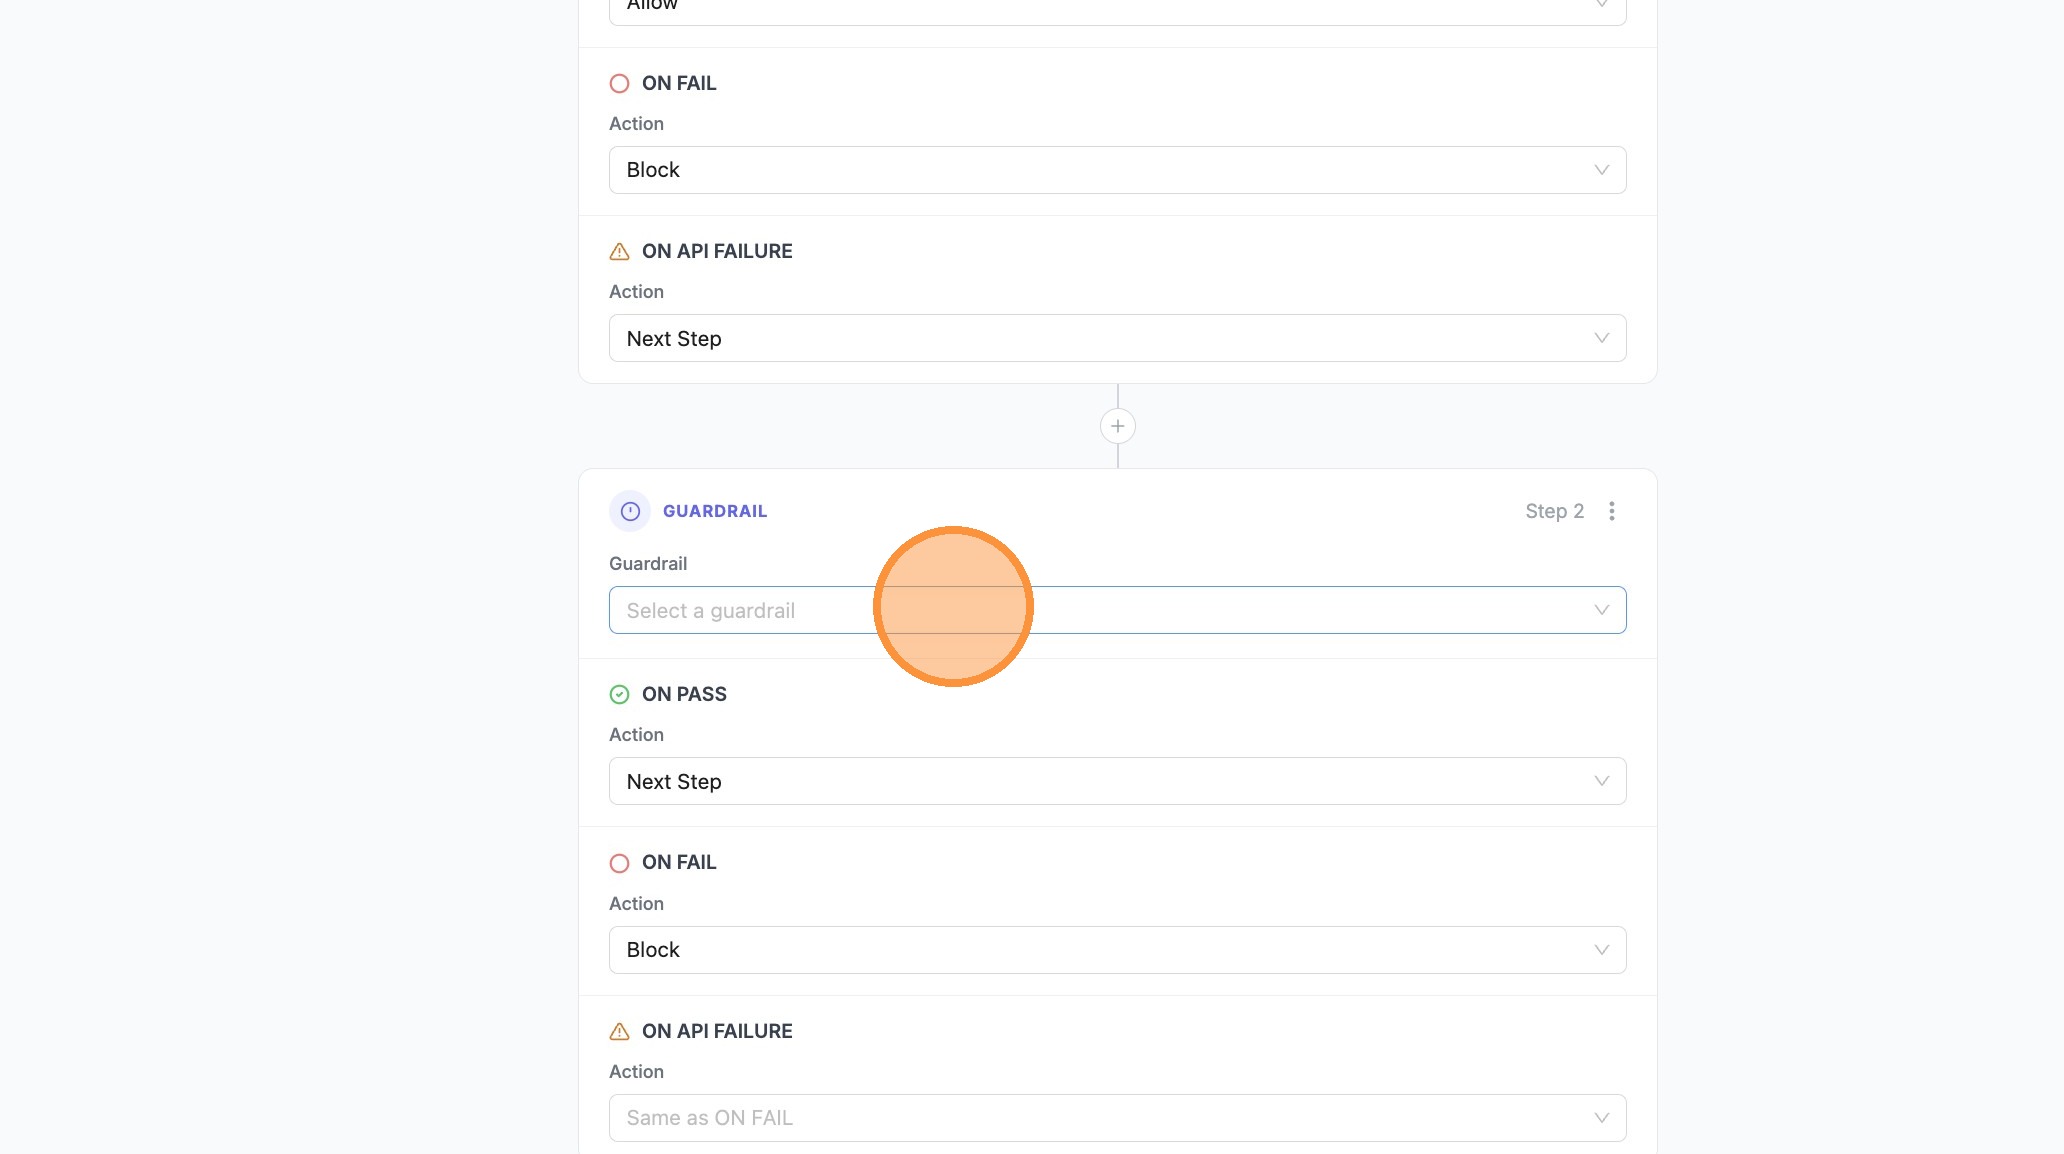
|
||||
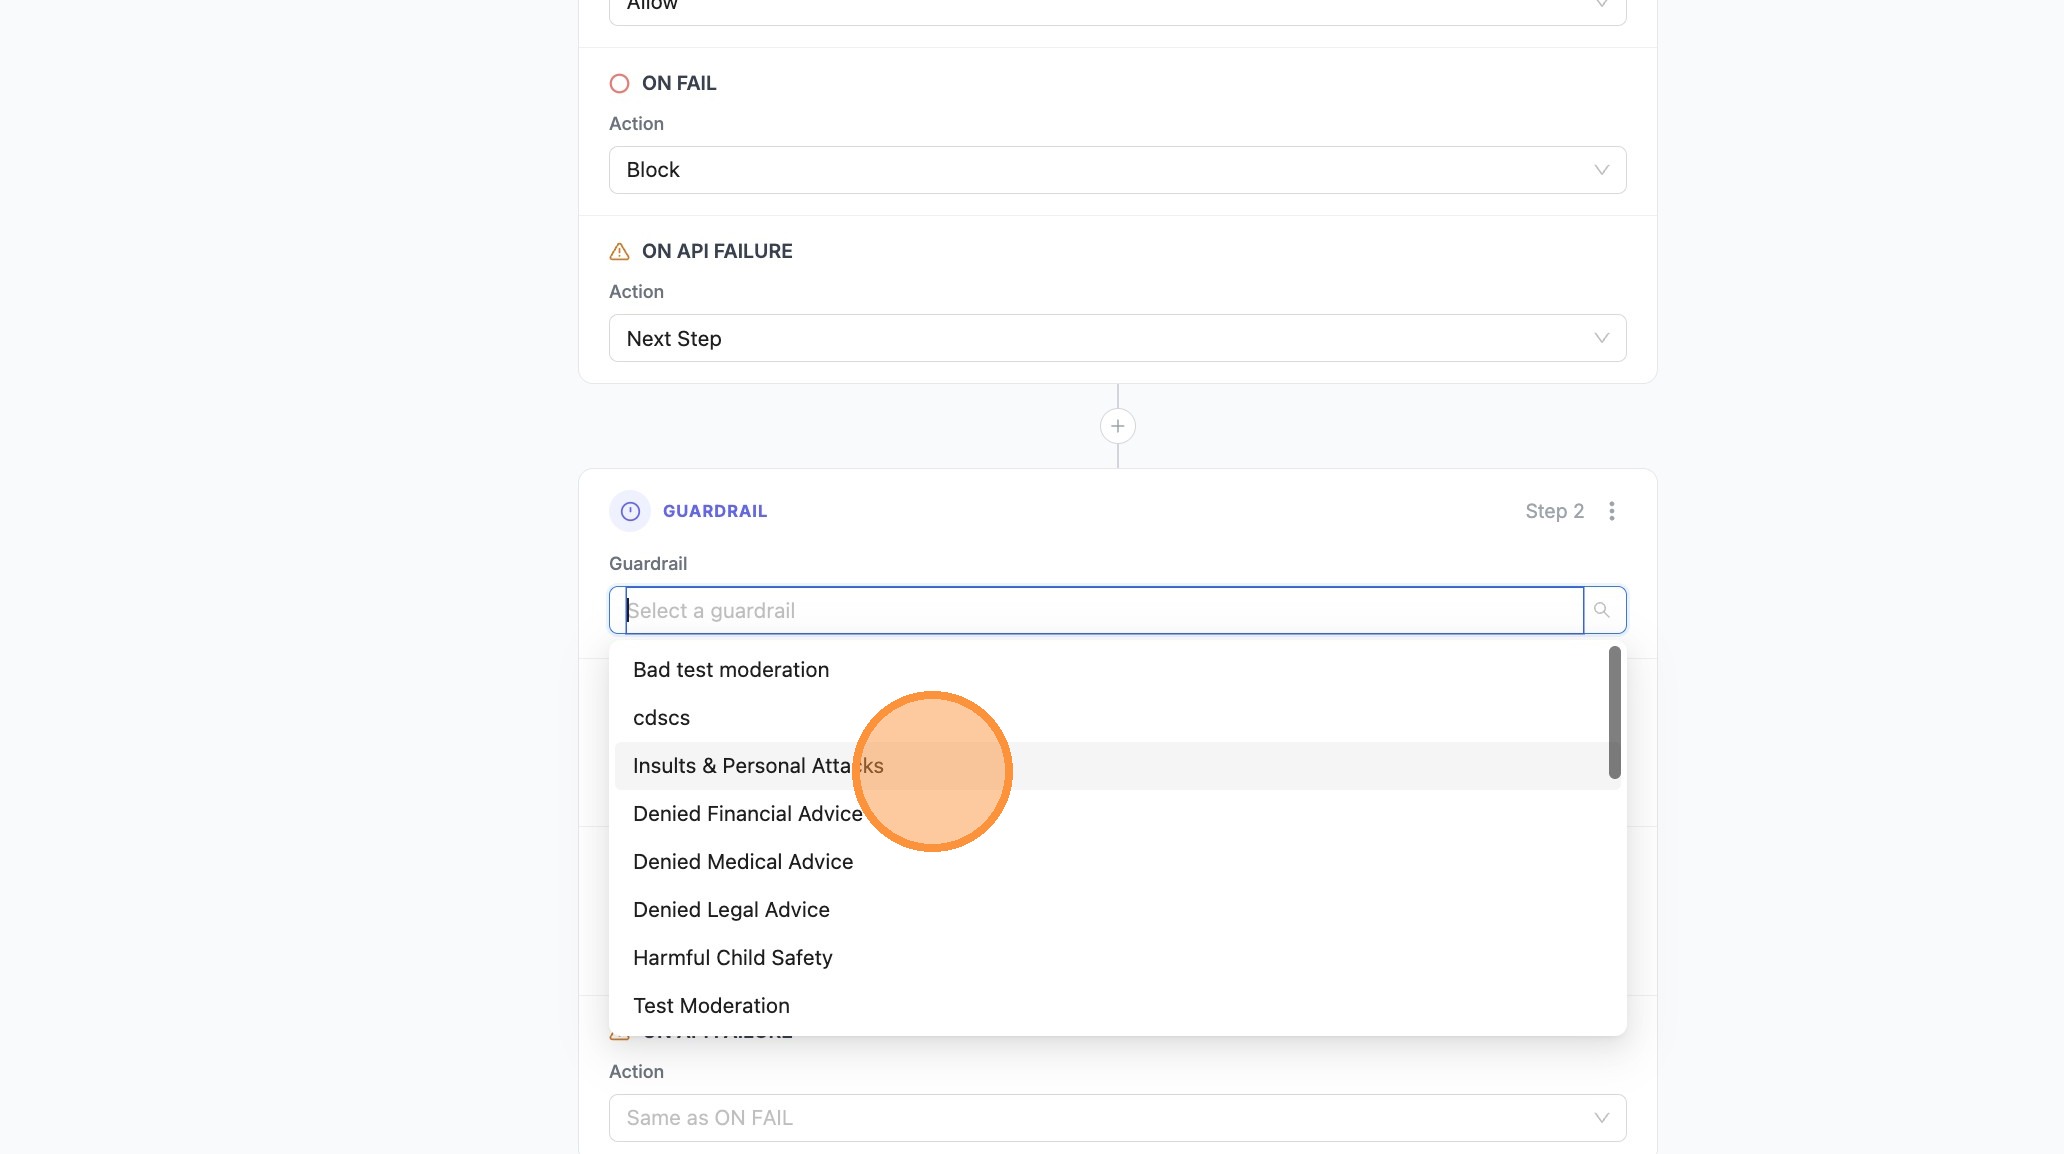
|
||||
13. Select **Insults & Personal Attacks** (or your fallback / stricter guardrail)
|
||||
|
||||
|
||||
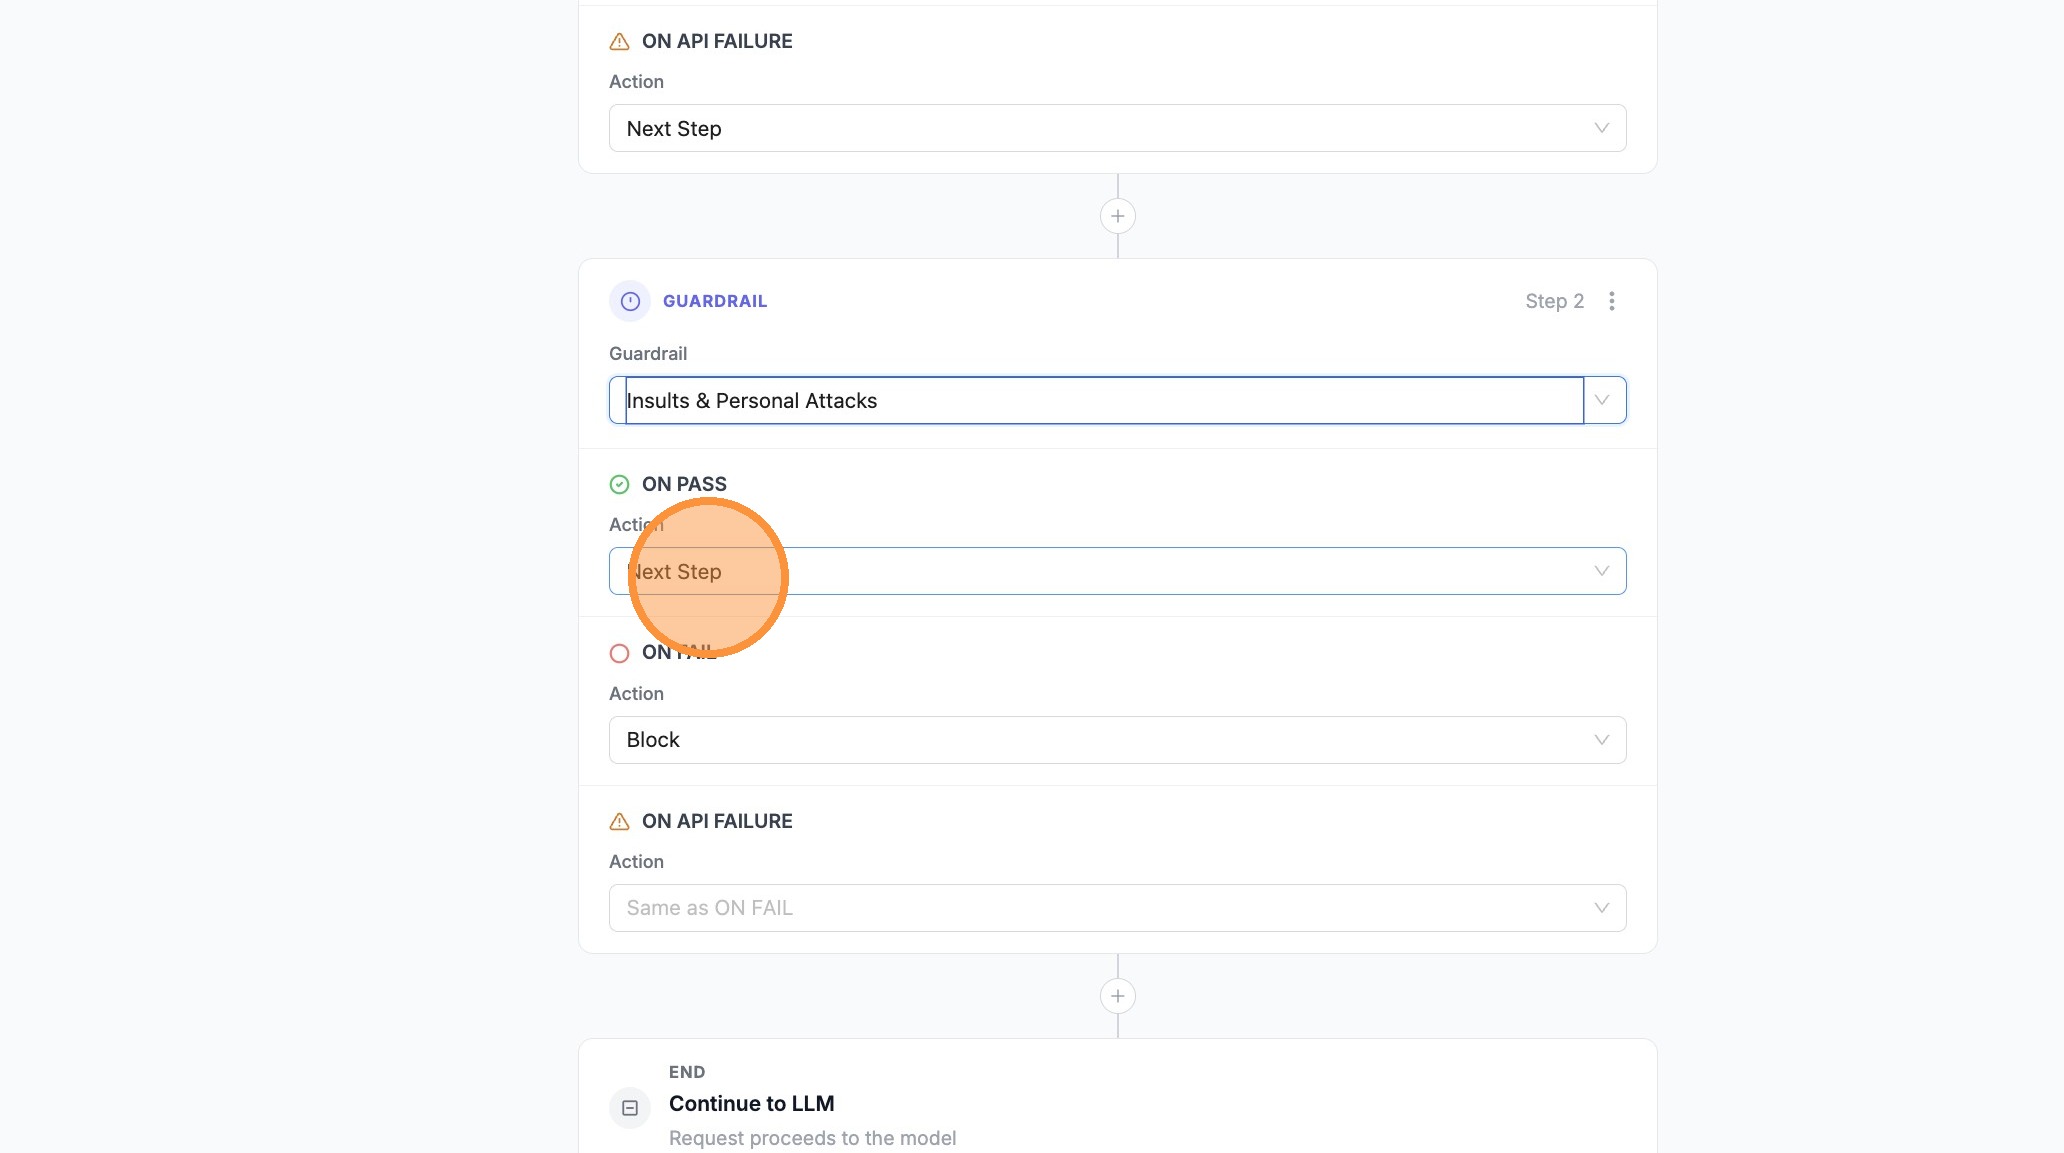
|
||||
14. Set **Next Step** or **Block** on the branches as needed for this step
|
||||
|
||||
|
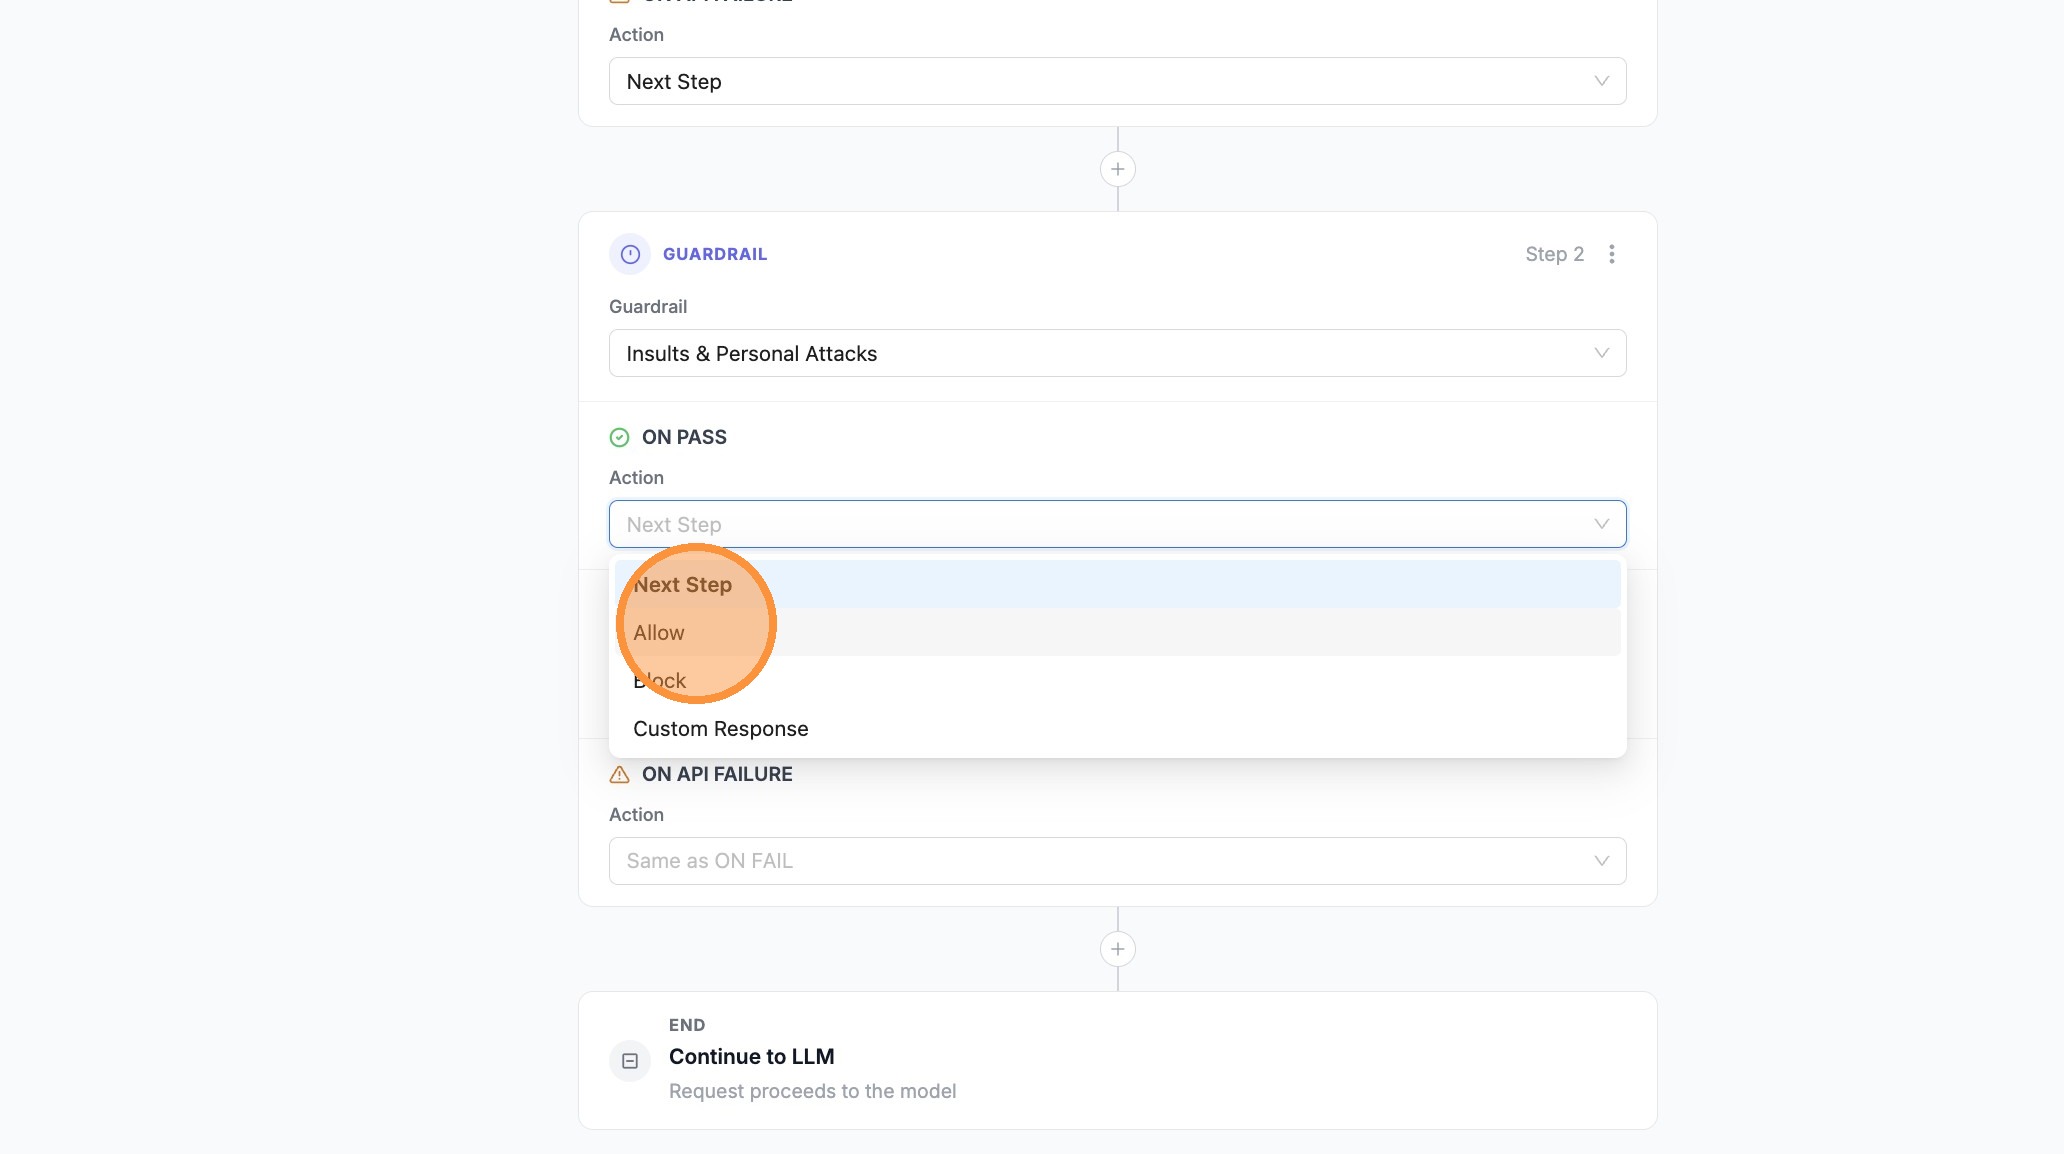
||||
|
||||
15. Set **ON PASS** to **Allow** when this guardrail should complete the pipeline successfully
|
||||
|
||||
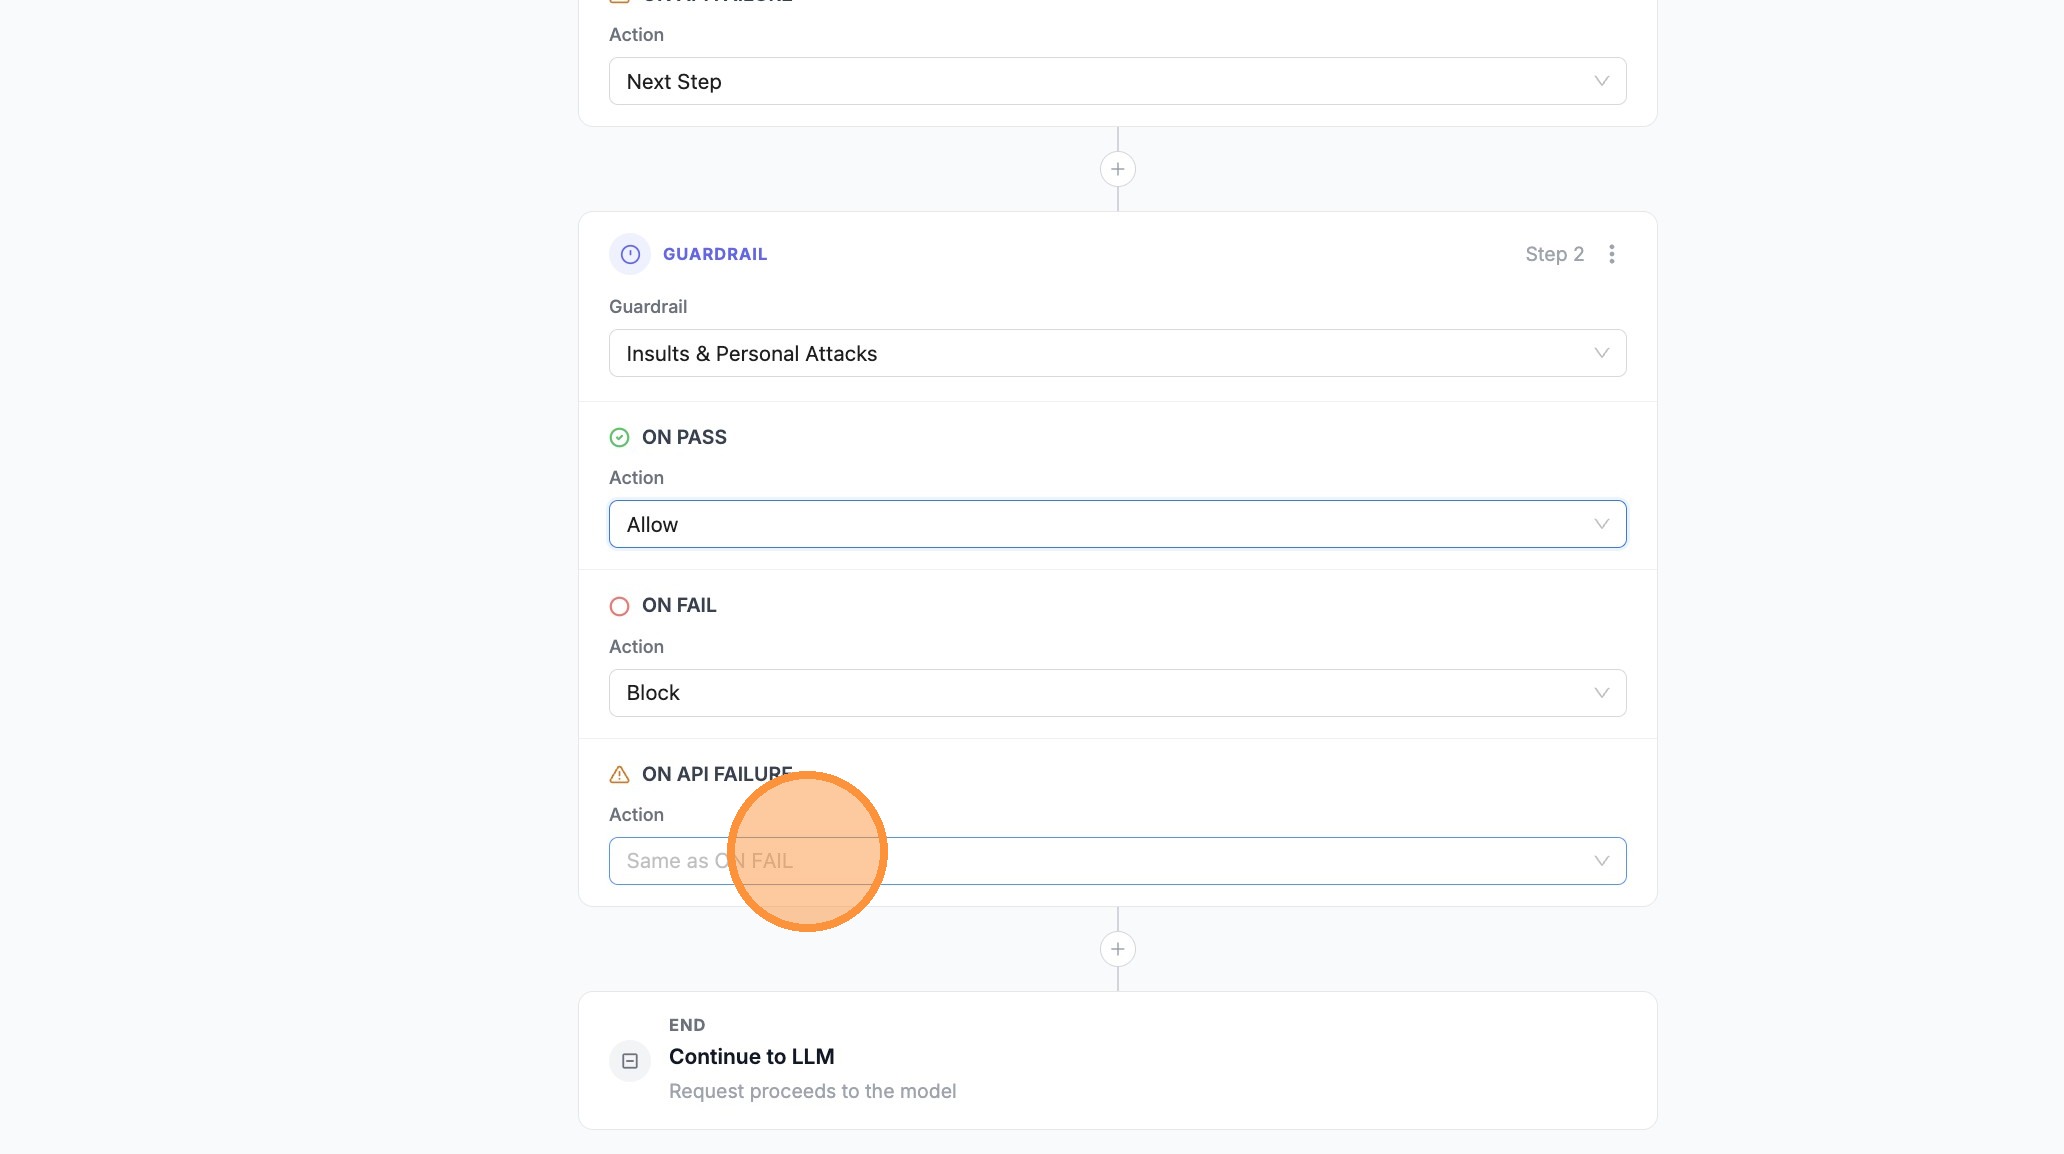
|
||||
|
||||
16. Open the branch where you want a **Custom Response** (e.g. **ON FAIL** on the last step)
|
||||
|
||||
|
||||
|
||||
17. Choose **Custom Response**
|
||||
|
||||
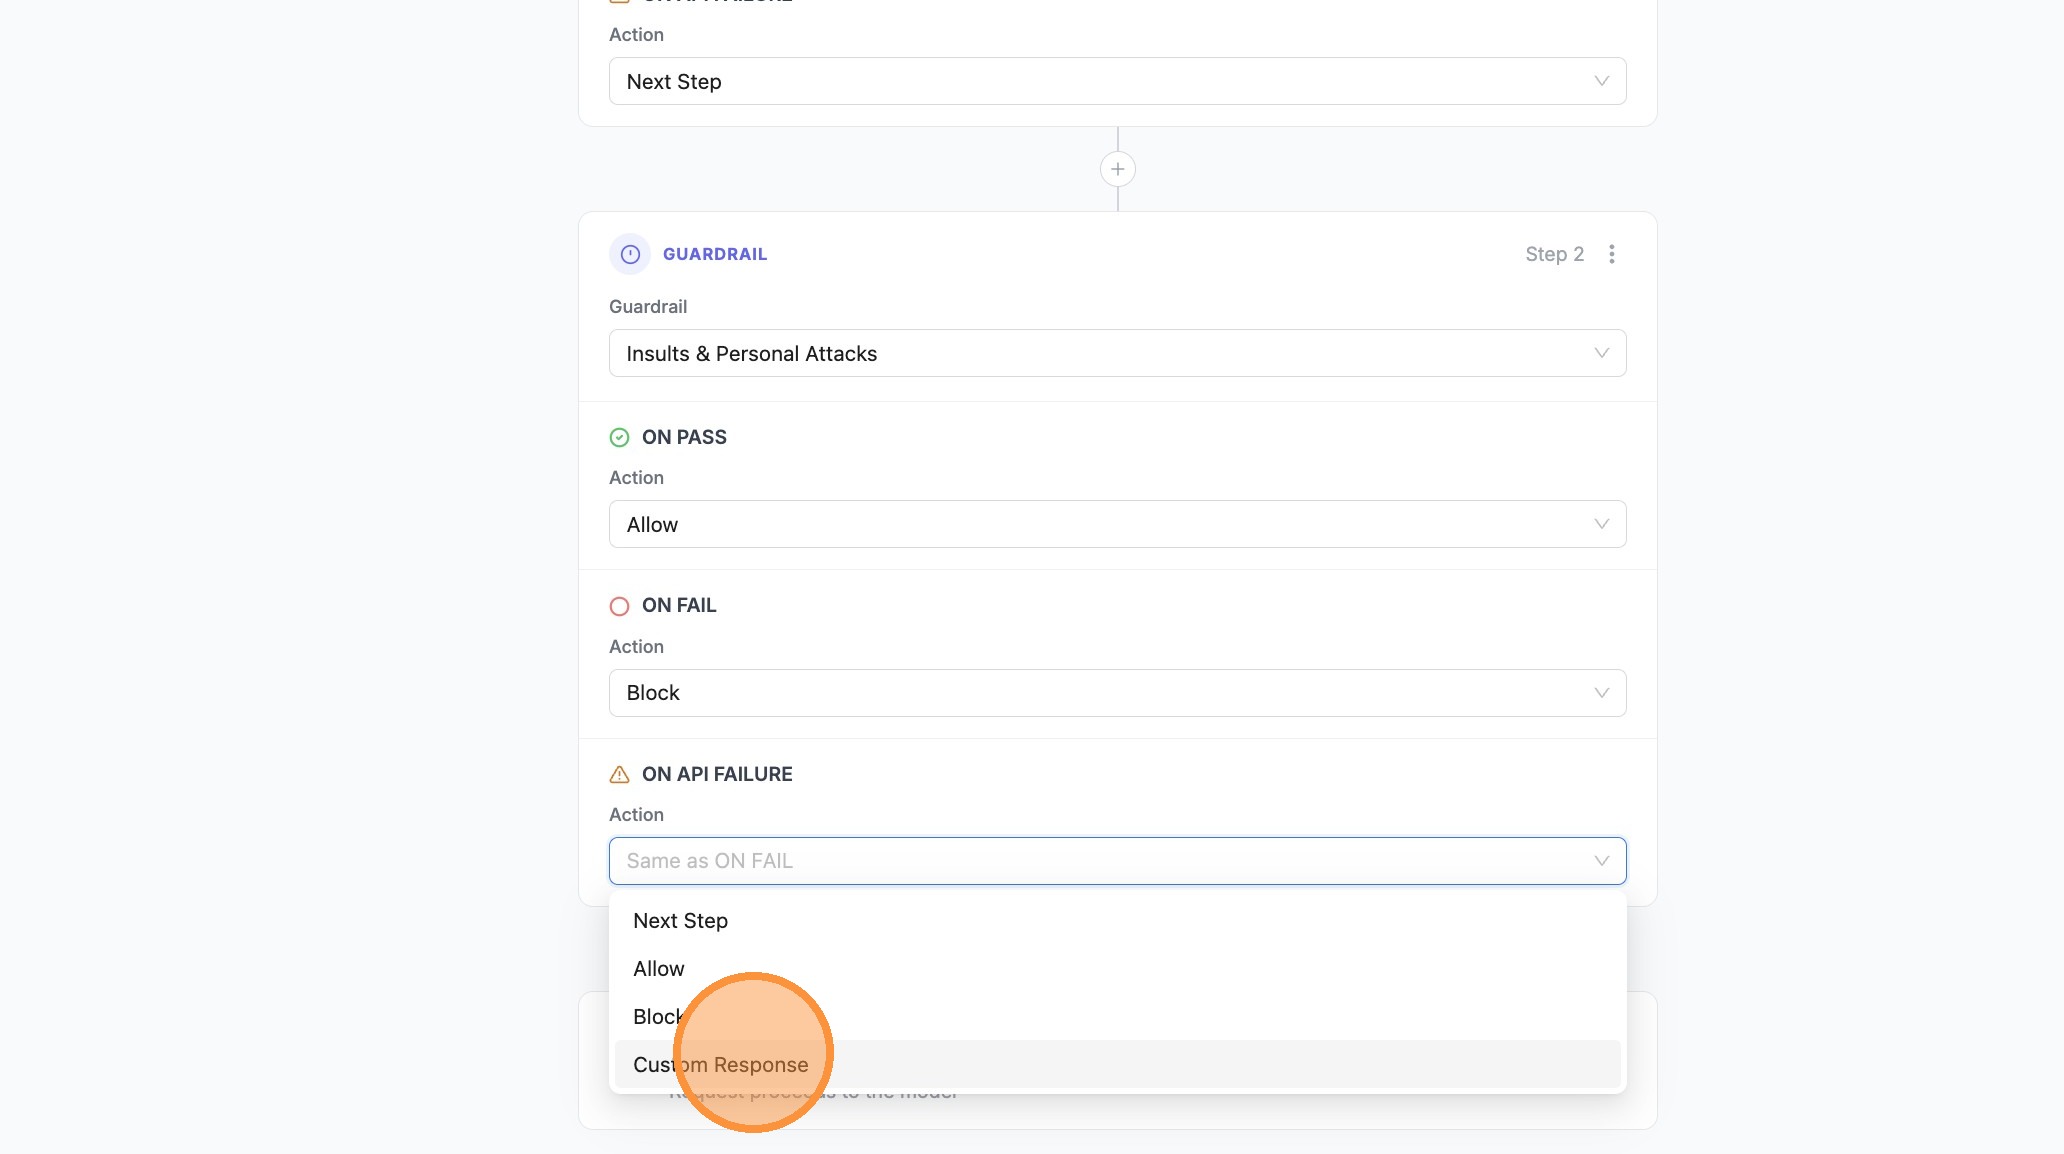
|
||||
|
||||
18. Click **Enter custom response...** and type your message
|
||||
|
||||
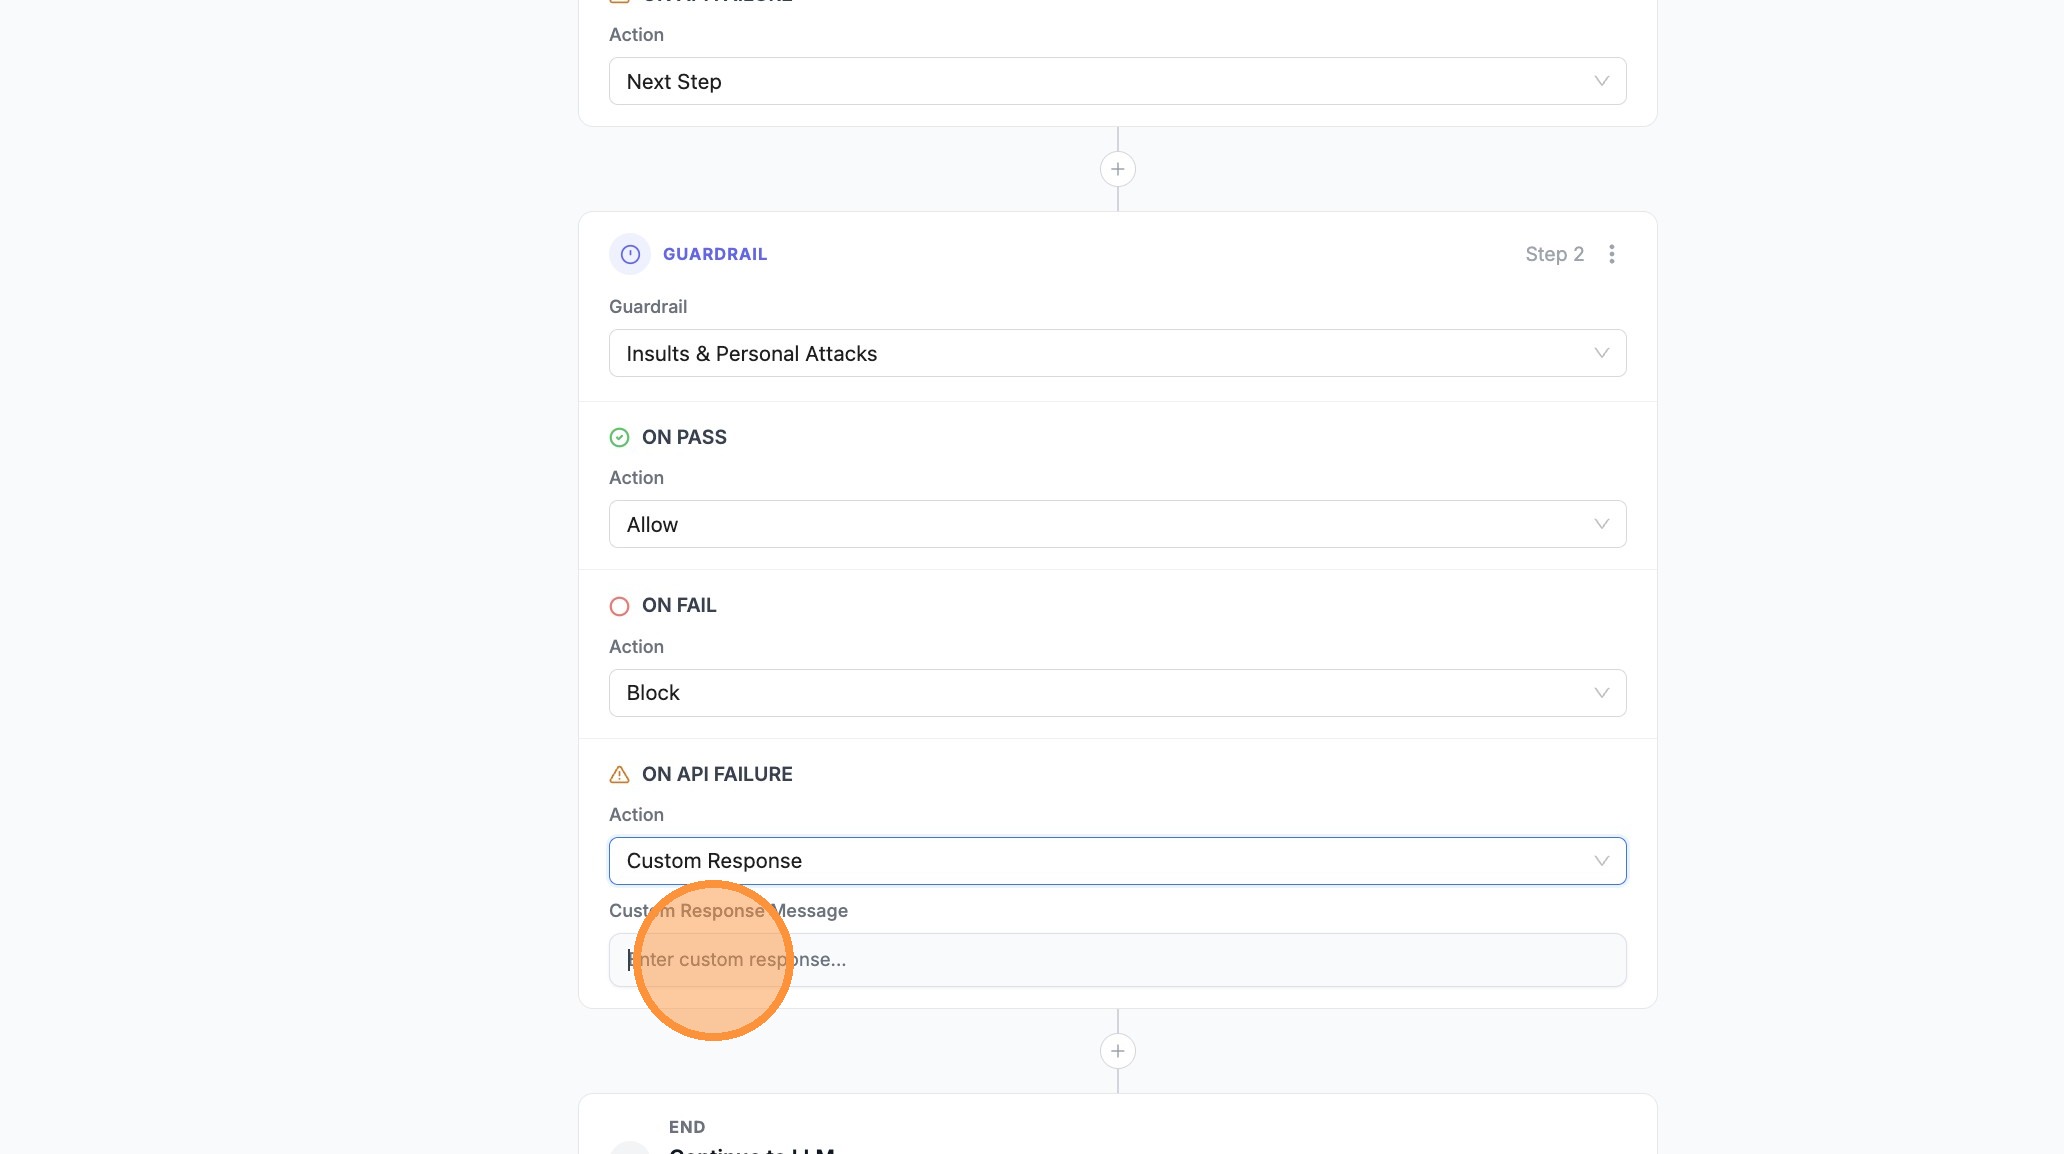
|
||||
|
||||
19. Confirm or edit the message in **Enter custom response...** as needed
|
||||
|
||||
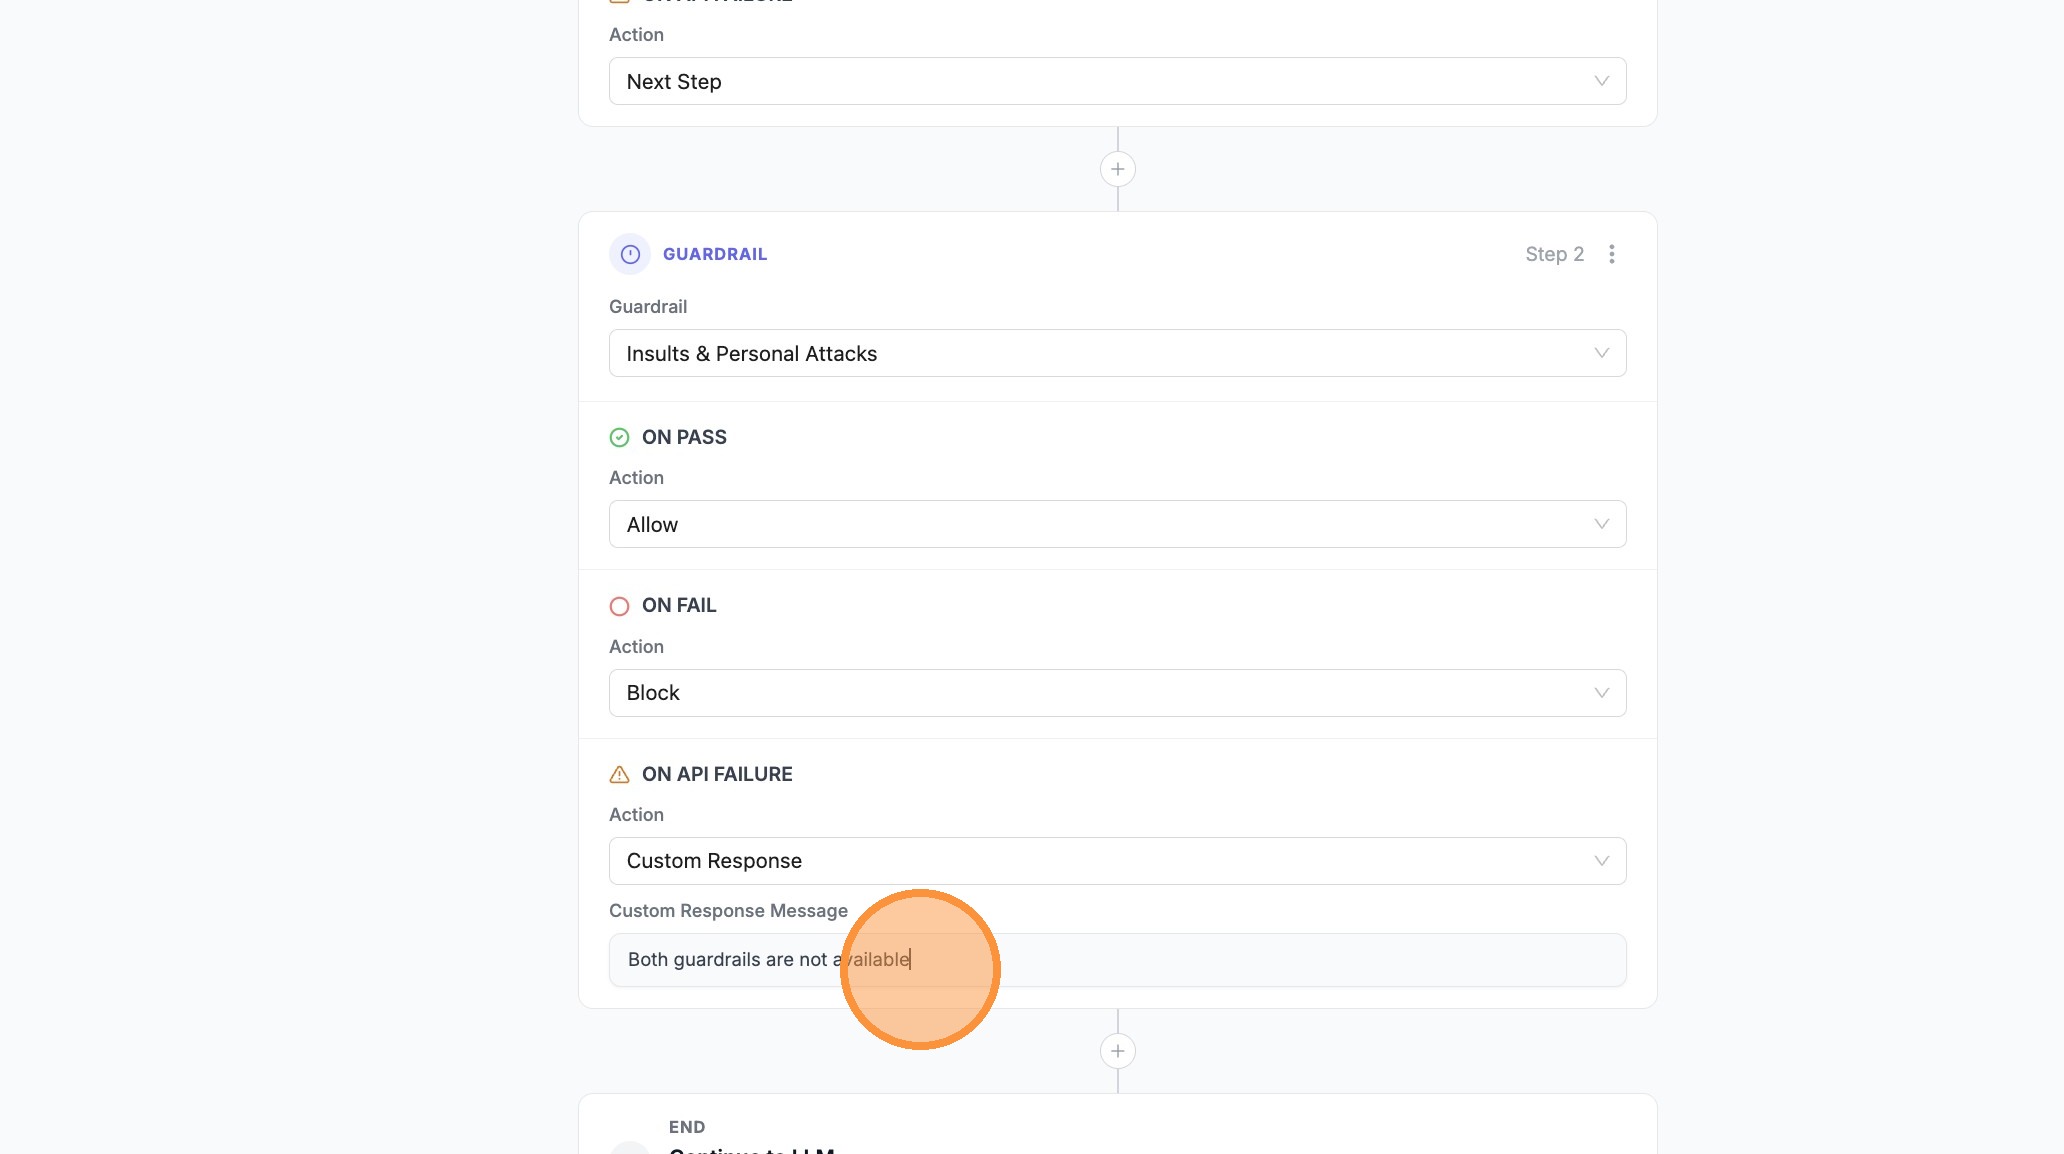
|
||||
|
||||
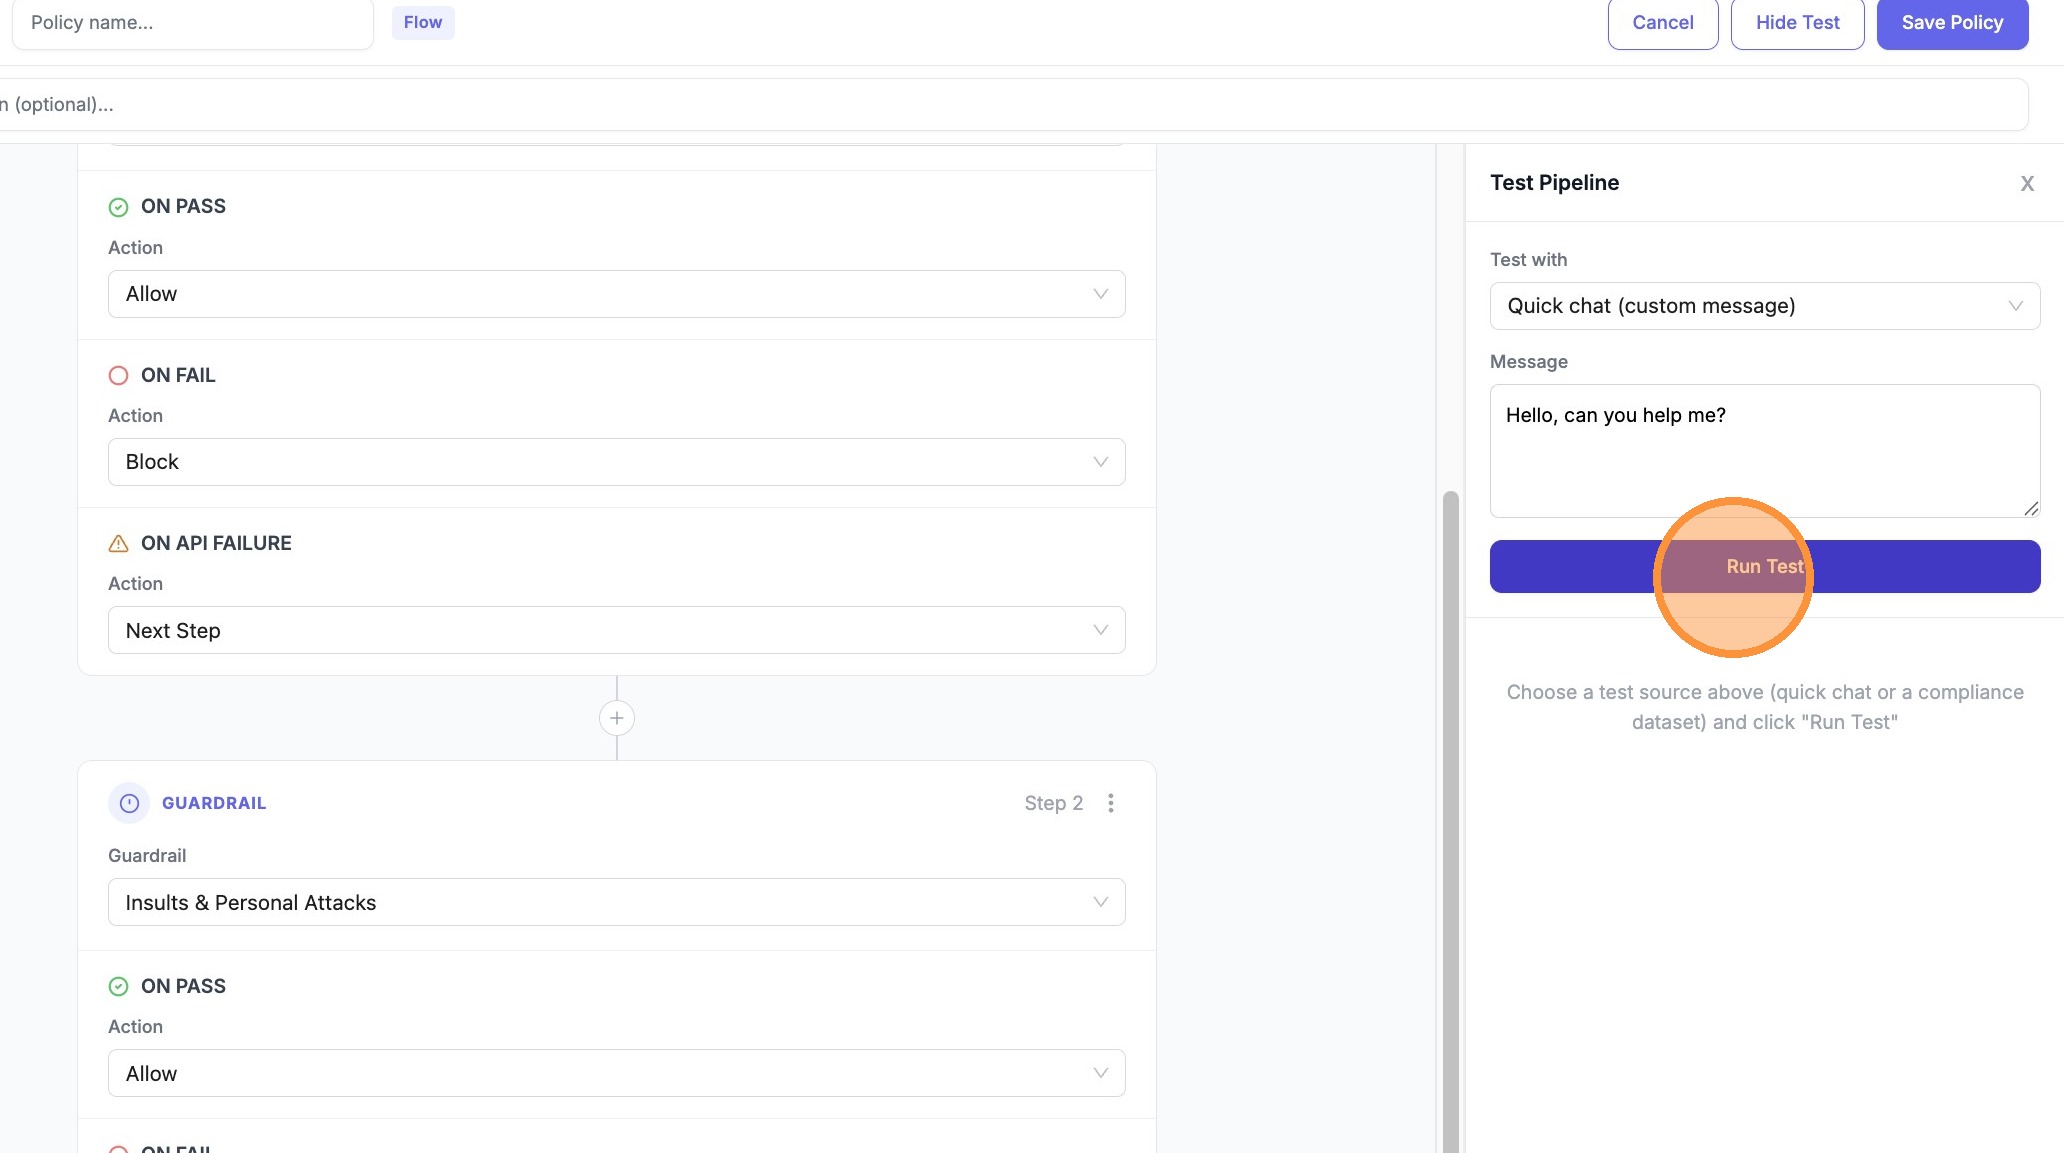
20. Open **Test Pipeline**
|
||||
|
||||
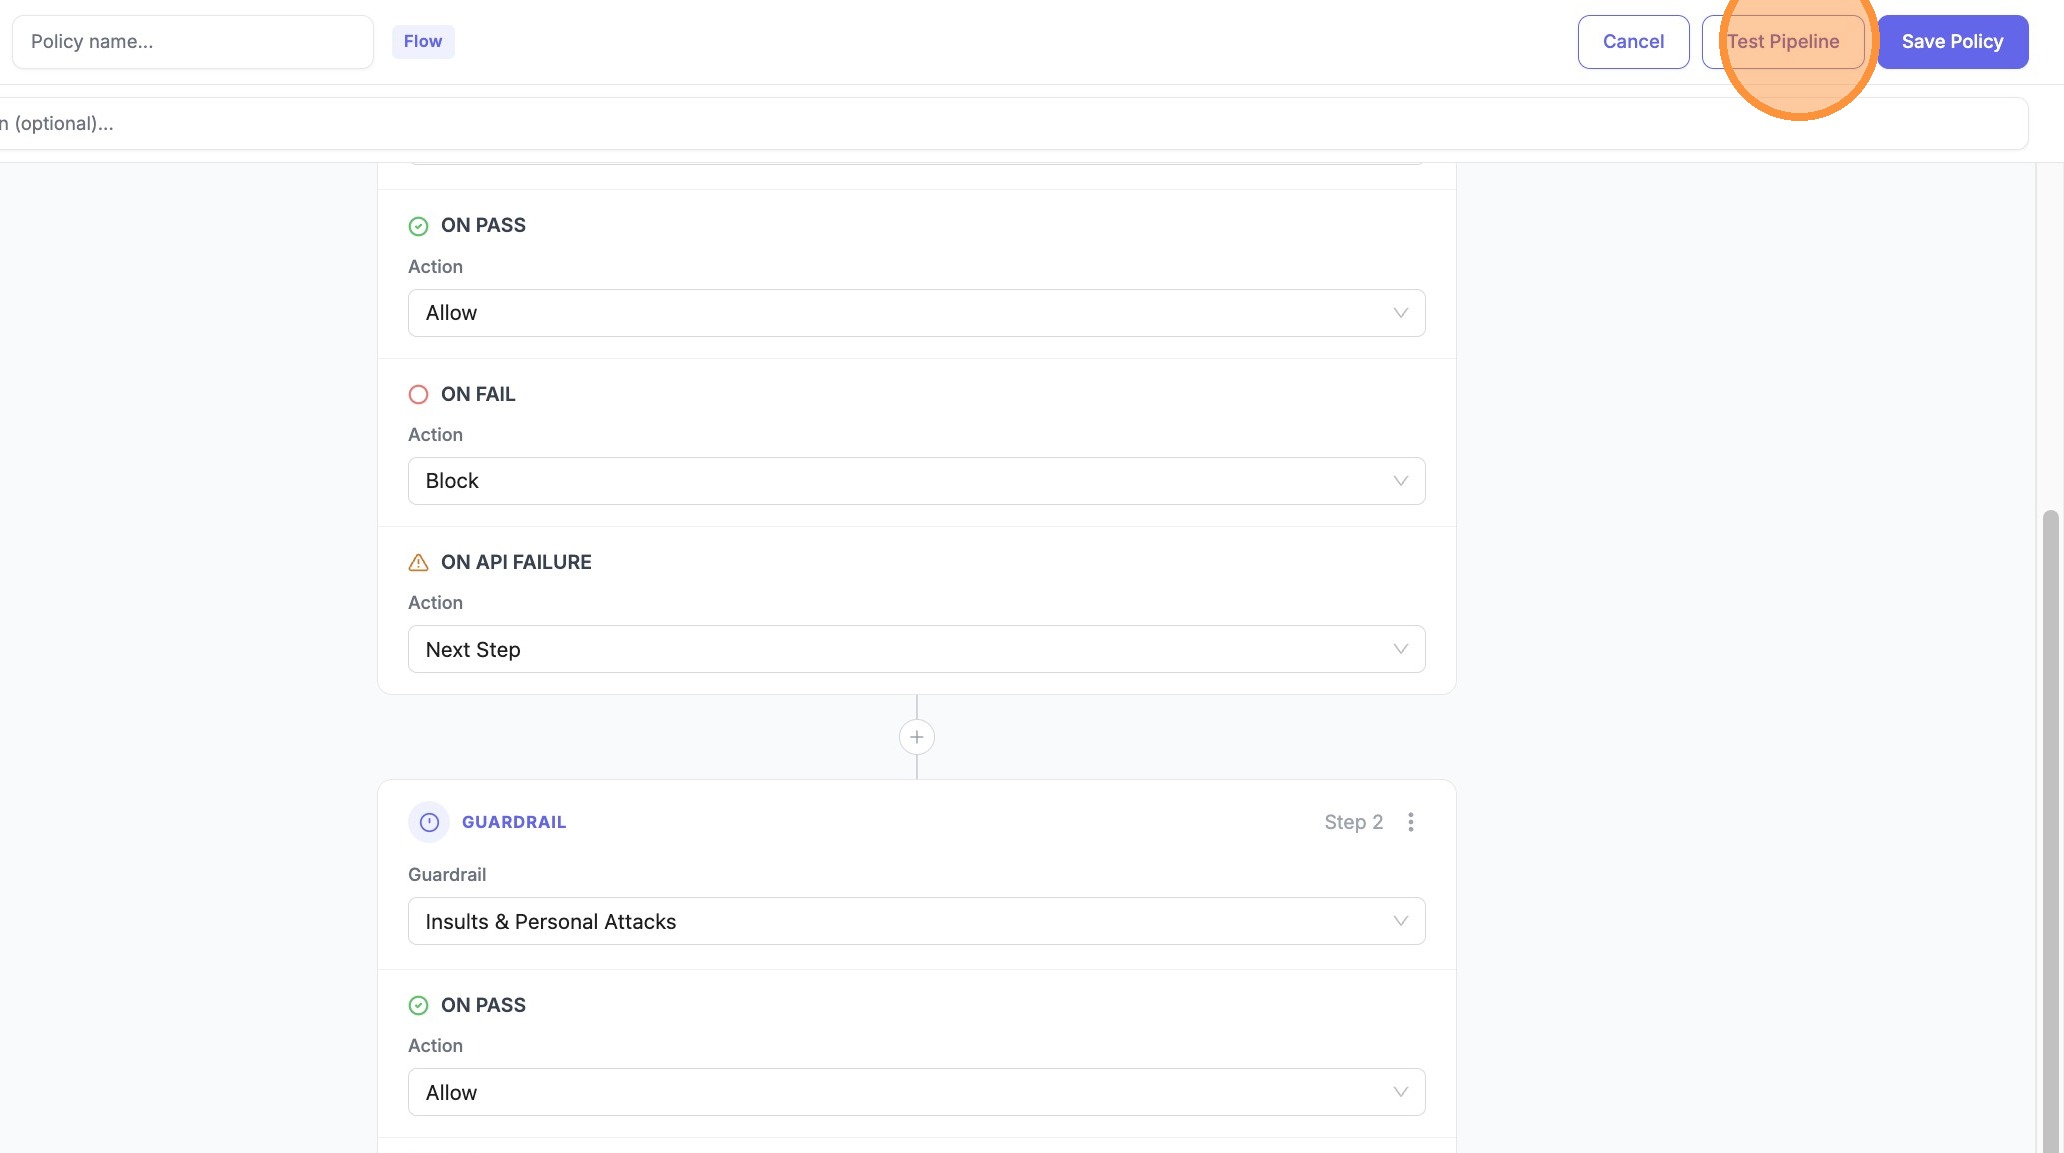
|
||||
|
||||
21. Click **Run Test**
|
||||
|
||||
|
||||
|
||||
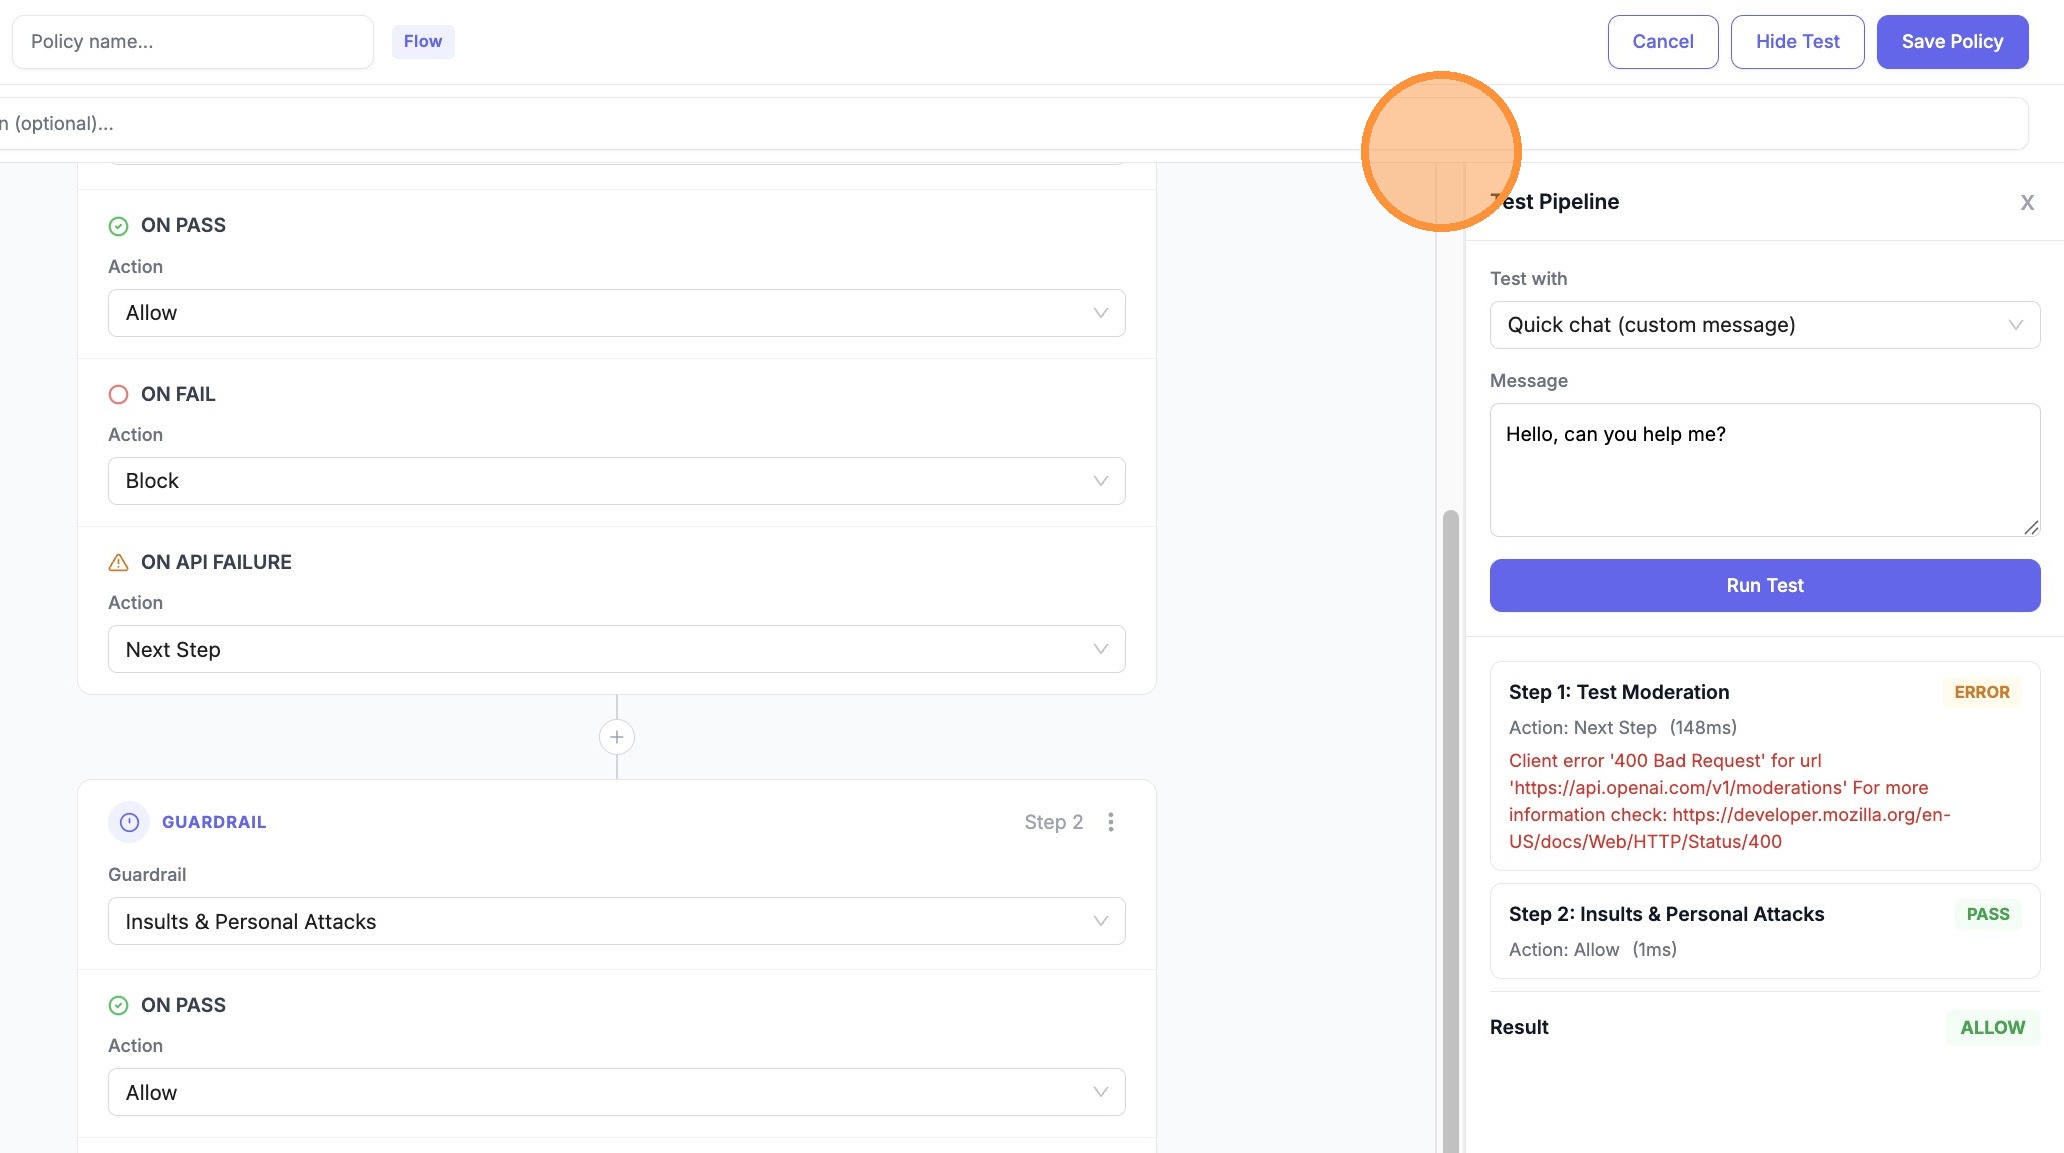
22. Expand **Step 1** (or the first guardrail row) in the results to see **ERROR** / **Next Step** vs **PASS** / **Allow**
|
||||
|
||||
|
||||
|
||||
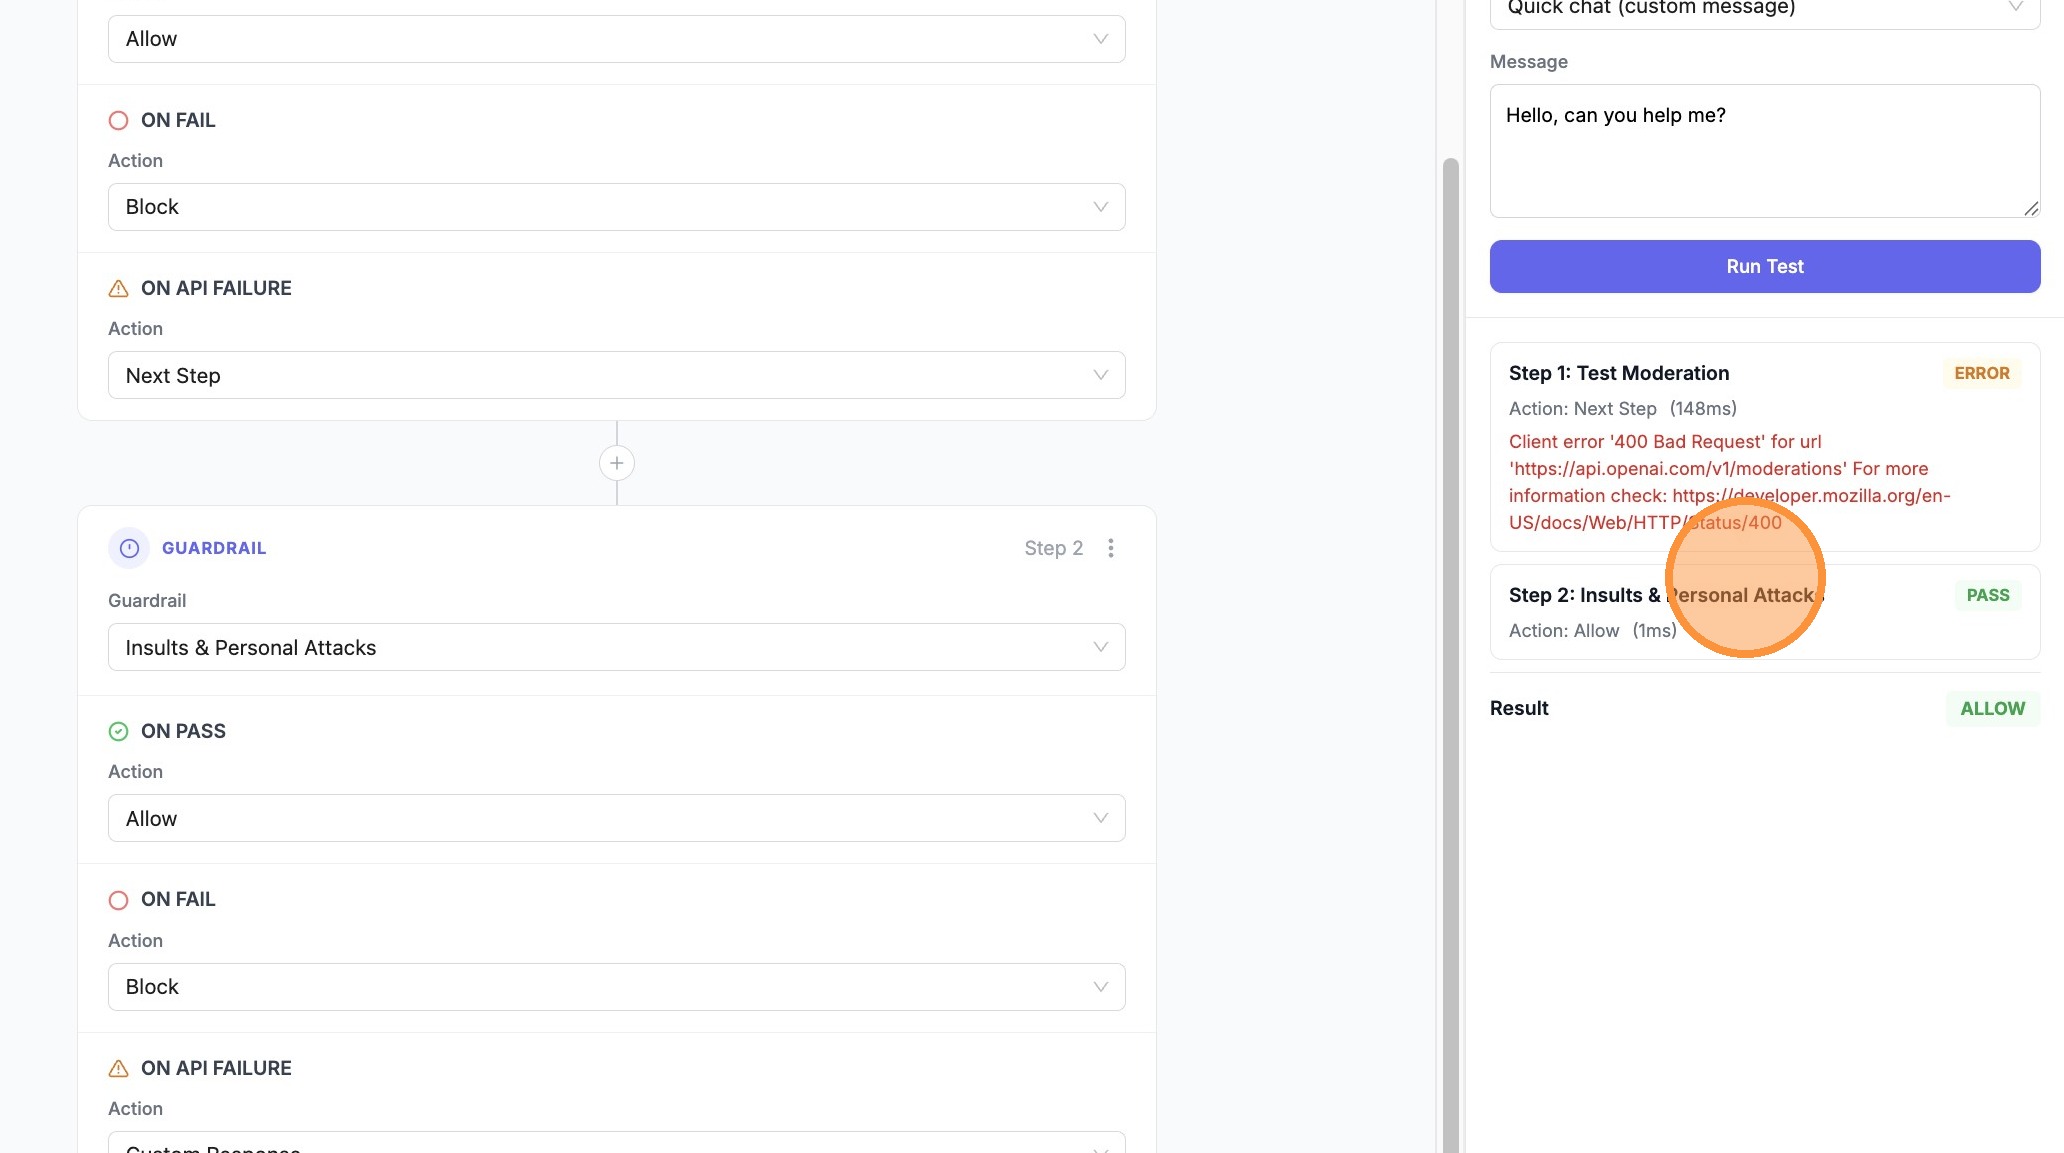
23. Expand **Step 2** (e.g. **Insults & Personal Attacks**) to confirm **PASS** and **Allow** after the fallback
|
||||
|
||||
|
||||
|
||||
## Config (YAML)
|
||||
|
||||
|
|
|
|||
|
|
@ -2,6 +2,16 @@ import Image from '@theme/IdealImage';
|
|||
|
||||
# Team Soft Budget Alerts
|
||||
|
||||
:::info
|
||||
|
||||
✨ This is an Enterprise feature. Email budget alerts require an enterprise license.
|
||||
|
||||
[Enterprise Pricing](https://www.litellm.ai/#pricing)
|
||||
|
||||
[Get free 7-day trial key](https://www.litellm.ai/enterprise#trial)
|
||||
|
||||
:::
|
||||
|
||||
Set a soft budget on a team and get email alerts when spending crosses the threshold — without blocking any requests.
|
||||
|
||||
## Overview
|
||||
|
|
|
|||
205
docs/my-website/docs/troubleshoot/cost_discrepancy.md
Normal file
205
docs/my-website/docs/troubleshoot/cost_discrepancy.md
Normal file
|
|
@ -0,0 +1,205 @@
|
|||
# Debugging a cost discrepancy
|
||||
|
||||
Cost discrepancies between LiteLLM and your provider bill usually come from one of three areas: token ingestion, the cost formula LiteLLM applies, or stale or incorrect pricing in the model map. This page walks through how to tell which case you are in.
|
||||
|
||||
## Step 1: Pick a time range
|
||||
|
||||
Lock down a specific window where the discrepancy is visible.
|
||||
|
||||
- Use at least 7 days of data when you can.
|
||||
- Prefer a window with stable usage so one-off spikes do not dominate the comparison.
|
||||
- Set the **same start and end time** on both your provider dashboard and the LiteLLM UI.
|
||||
|
||||

|
||||
|
||||
## Step 2: Confirm traffic only goes through LiteLLM
|
||||
|
||||
If any requests hit the provider directly (bypassing LiteLLM), the provider will show higher usage. That is expected, not a LiteLLM bug.
|
||||
|
||||
Before continuing, confirm:
|
||||
|
||||
- All clients use your LiteLLM proxy base URL.
|
||||
- No SDK or script uses provider API keys against the provider directly for the models you are comparing.
|
||||
- During the selected period, the models in question are only called via LiteLLM.
|
||||
|
||||
If you are unsure, filter the provider dashboard by the API key or IAM principal LiteLLM uses, rather than comparing to your whole account.
|
||||
|
||||
## Step 3: Compare token categories
|
||||
|
||||
In the LiteLLM UI, open **Model activity** (under Usage analytics) so you can inspect spend and tokens per model.
|
||||
|
||||

|
||||
|
||||
Scroll the **Model** list and select the model you are reconciling with your provider bill.
|
||||
|
||||

|
||||
|
||||
With the same time range on both sides, fill in:
|
||||
|
||||
| Category | LiteLLM | Provider | Delta |
|
||||
| --- | --- | --- | --- |
|
||||
| Total requests | — | — | — |
|
||||
| Input tokens | — | — | — |
|
||||
| Output tokens | — | — | — |
|
||||
| Cache read tokens | — | — | — |
|
||||
| Cache write tokens | — | — | — |
|
||||
|
||||
LiteLLM surfaces per-category token usage for the selected model—for example prompt, completion, and cache-related tokens.
|
||||
|
||||

|
||||
|
||||
Compare these figures with your provider’s usage view (for example AWS billing tools, Azure Monitor, or the OpenAI usage dashboard) for the same period.
|
||||
|
||||
### Cache token reporting
|
||||
|
||||
- **OpenAI:** Cache read tokens are typically included inside the reported input token count.
|
||||
- **Anthropic:** Cache read tokens are often reported separately from non-cached input tokens.
|
||||
|
||||
Compare the correct columns on each side so you are not treating “input” differently between dashboards.
|
||||
|
||||
### Why use a 10% threshold?
|
||||
|
||||
Provider dashboards and LiteLLM do not bucket requests on identical timestamps. A call at 11:59 PM can land in different daily totals on each side. Token counts can also differ slightly due to rounding across SDKs and APIs. A delta **under ~10%** is often explained by boundary effects and rounding. A delta **over ~10%** usually means something is miscounted, dropped, or categorized differently.
|
||||
|
||||
## Step 4: Follow the right path
|
||||
|
||||
<svg width="100%" viewBox="0 0 680 482" role="img" xmlns="http://www.w3.org/2000/svg" style={{ maxWidth: '100%', fontFamily: 'system-ui, sans-serif' }} aria-labelledby="cost-disc-flow-title">
|
||||
<title id="cost-disc-flow-title">Cost discrepancy debugging flowchart</title>
|
||||
<desc>Flowchart branching into Path A (token ingestion) or Path B which splits further into B1 (formula issue) and B2 (model map issue).</desc>
|
||||
<defs>
|
||||
<marker id="cd-arrow" viewBox="0 0 10 10" refX="8" refY="5" markerWidth="6" markerHeight="6" orient="auto-start-reverse">
|
||||
<path d="M2 1L8 5L2 9" fill="none" stroke="#888780" strokeWidth="1.5" strokeLinecap="round" strokeLinejoin="round" />
|
||||
</marker>
|
||||
</defs>
|
||||
|
||||
<rect x="215" y="24" width="250" height="44" rx="8" fill="#F1EFE8" stroke="#5F5E5A" strokeWidth="0.5" />
|
||||
<text x="340" y="47" textAnchor="middle" dominantBaseline="central" fill="#444441" fontSize="14" fontWeight="500">Compare provider vs LiteLLM</text>
|
||||
|
||||
<line x1="340" y1="68" x2="340" y2="104" stroke="#888780" strokeWidth="1.5" markerEnd="url(#cd-arrow)" />
|
||||
|
||||
<rect x="175" y="104" width="330" height="56" rx="8" fill="#F1EFE8" stroke="#5F5E5A" strokeWidth="0.5" />
|
||||
<text x="340" y="126" textAnchor="middle" dominantBaseline="central" fill="#444441" fontSize="14" fontWeight="500">Any category off by > 10%?</text>
|
||||
<text x="340" y="148" textAnchor="middle" dominantBaseline="central" fill="#5F5E5A" fontSize="12">requests, input, output, cache tokens</text>
|
||||
|
||||
<path d="M220 132 L100 132 L100 250" fill="none" stroke="#0F6E56" strokeWidth="1.5" markerEnd="url(#cd-arrow)" />
|
||||
<text x="157" y="122" textAnchor="middle" fill="#0F6E56" fontSize="12">YES</text>
|
||||
|
||||
<path d="M505 132 L580 132 L580 250" fill="none" stroke="#993C1D" strokeWidth="1.5" markerEnd="url(#cd-arrow)" />
|
||||
<text x="543" y="122" textAnchor="middle" fill="#993C1D" fontSize="12">NO</text>
|
||||
|
||||
<rect x="40" y="250" width="220" height="56" rx="8" fill="#E1F5EE" stroke="#0F6E56" strokeWidth="0.5" />
|
||||
<text x="150" y="271" textAnchor="middle" dominantBaseline="central" fill="#085041" fontSize="14" fontWeight="500">Path A</text>
|
||||
<text x="150" y="291" textAnchor="middle" dominantBaseline="central" fill="#0F6E56" fontSize="12">Token ingestion issue</text>
|
||||
|
||||
<rect x="420" y="250" width="220" height="56" rx="8" fill="#FAECE7" stroke="#993C1D" strokeWidth="0.5" />
|
||||
<text x="530" y="271" textAnchor="middle" dominantBaseline="central" fill="#712B13" fontSize="14" fontWeight="500">Path B</text>
|
||||
<text x="530" y="291" textAnchor="middle" dominantBaseline="central" fill="#993C1D" fontSize="12">Quantities match, cost differs</text>
|
||||
|
||||
<line x1="150" y1="306" x2="150" y2="370" stroke="#0F6E56" strokeWidth="1.5" markerEnd="url(#cd-arrow)" />
|
||||
|
||||
<line x1="530" y1="306" x2="530" y2="318" stroke="#854F0B" strokeWidth="1.5" />
|
||||
<line x1="435" y1="318" x2="575" y2="318" stroke="#854F0B" strokeWidth="1.5" />
|
||||
<line x1="435" y1="318" x2="435" y2="370" stroke="#854F0B" strokeWidth="1.5" markerEnd="url(#cd-arrow)" />
|
||||
<line x1="575" y1="318" x2="575" y2="370" stroke="#854F0B" strokeWidth="1.5" markerEnd="url(#cd-arrow)" />
|
||||
<text x="448" y="312" textAnchor="middle" fill="#854F0B" fontSize="11">B1</text>
|
||||
<text x="562" y="312" textAnchor="middle" fill="#854F0B" fontSize="11">B2</text>
|
||||
|
||||
<rect x="40" y="370" width="220" height="56" rx="8" fill="#E1F5EE" stroke="#0F6E56" strokeWidth="0.5" />
|
||||
<text x="150" y="391" textAnchor="middle" dominantBaseline="central" fill="#085041" fontSize="14" fontWeight="500">Report to LiteLLM team</text>
|
||||
<text x="150" y="411" textAnchor="middle" dominantBaseline="central" fill="#0F6E56" fontSize="12">endpoints + model + screenshots</text>
|
||||
|
||||
<rect x="380" y="370" width="110" height="56" rx="8" fill="#FAEEDA" stroke="#854F0B" strokeWidth="0.5" />
|
||||
<text x="435" y="391" textAnchor="middle" dominantBaseline="central" fill="#633806" fontSize="14" fontWeight="500">B1</text>
|
||||
<text x="435" y="411" textAnchor="middle" dominantBaseline="central" fill="#854F0B" fontSize="12">Fix formula</text>
|
||||
|
||||
<rect x="510" y="370" width="130" height="56" rx="8" fill="#FAEEDA" stroke="#854F0B" strokeWidth="0.5" />
|
||||
<text x="575" y="391" textAnchor="middle" dominantBaseline="central" fill="#633806" fontSize="14" fontWeight="500">B2</text>
|
||||
<text x="575" y="411" textAnchor="middle" dominantBaseline="central" fill="#854F0B" fontSize="12">Fix model map</text>
|
||||
|
||||
<path d="M150 426 L150 442 L340 442" fill="none" stroke="#888780" strokeWidth="0.5" strokeDasharray="4 3" />
|
||||
<path d="M340 442 L435 442 L435 428" fill="none" stroke="#888780" strokeWidth="0.5" strokeDasharray="4 3" />
|
||||
<path d="M340 442 L575 442 L575 428" fill="none" stroke="#888780" strokeWidth="0.5" strokeDasharray="4 3" />
|
||||
<text x="340" y="454" textAnchor="middle" fill="#5F5E5A" fontSize="11">if neither path resolves it,</text>
|
||||
<text x="340" y="470" textAnchor="middle" fill="#5F5E5A" fontSize="11">Open a github issue backing up with all your data</text>
|
||||
</svg>
|
||||
|
||||
## Path A: Token quantity mismatch
|
||||
|
||||
If any category is off by more than about 10%, LiteLLM may not be ingesting that category correctly (or the provider dashboard is categorizing tokens differently—recheck Step 3 first).
|
||||
|
||||
**What to send the LiteLLM team:**
|
||||
|
||||
1. Screenshots of both dashboards with the date range visible.
|
||||
2. Which category is off (input, output, cache reads, cache writes, or request count).
|
||||
3. Endpoints used (for example `/chat/completions`, `/responses`, `/embeddings`).
|
||||
4. Model names as sent in the request (for example `anthropic.claude-opus-4-5`, `gpt-4o`).
|
||||
|
||||
### For maintainers debugging ingestion
|
||||
|
||||
1. Start the proxy with verbose logging, for example:
|
||||
```bash
|
||||
litellm --config config.yaml --detailed_debug
|
||||
```
|
||||
2. Reproduce a single request with the reported endpoint and model.
|
||||
3. Inspect the raw `usage` object in each streamed chunk (if streaming) or in the final response body.
|
||||
4. Compare that to the standard logging object (or the UI request log for that call).
|
||||
5. Any gap between raw provider usage and what LiteLLM logs or aggregates is where ingestion may be wrong.
|
||||
|
||||
## Path B: Quantities match but cost is wrong
|
||||
|
||||
If token and request counts agree within ~10% but dollar amounts differ, focus on how cost is computed.
|
||||
|
||||
### B1: Formula issue
|
||||
|
||||
Manually compute expected cost using the provider’s token breakdown and published rates (per million tokens or per token).
|
||||
|
||||
Add other billed dimensions your provider applies (for example cache creation, audio, or tier surcharges). If your hand calculation matches the provider bill but not LiteLLM, the implementation in LiteLLM for that provider or modality may be wrong.
|
||||
|
||||
### B2: Model map issue
|
||||
|
||||
If the formula structure matches how the provider bills, the values in LiteLLM’s model map may be stale or incorrect. Cross-check:
|
||||
|
||||
- [`model_prices_and_context_window.json`](https://github.com/BerriAI/litellm/blob/main/model_prices_and_context_window.json)
|
||||
- The provider’s current public pricing
|
||||
|
||||
Inspect `input_cost_per_token`, `output_cost_per_token`, and any cache-related pricing fields for your exact model id (including provider prefix).
|
||||
|
||||
### For maintainers
|
||||
|
||||
1. Take authoritative token quantities from the user’s provider report.
|
||||
2. Derive the formula that reproduces the provider’s line item.
|
||||
3. Diff that against LiteLLM’s cost path for the same provider and response shape.
|
||||
4. If the formula matches but numbers differ, update pricing in `model_prices_and_context_window.json` (and follow the project’s sync / backup rules for that file).
|
||||
5. If the formula in code is wrong, fix the calculation and add a regression test using the user’s token breakdown.
|
||||
|
||||
## Still stuck?
|
||||
|
||||
1. Open a GitHub issue on [BerriAI/litellm](https://github.com/BerriAI/litellm) with your Step 3 comparison table, endpoints, and model names.
|
||||
|
||||
|
||||
On the issue, it helps to clarify:
|
||||
|
||||
- Reproducible on demand or intermittent?
|
||||
- Single model or many?
|
||||
- Steady over time, or starting from a specific release date or config change?
|
||||
|
||||
### For LiteLLM maintainers
|
||||
|
||||
If Path A and Path B do not close the case after triage, **you** should reach out and **schedule a call with the customer** (support or engineering), with the Step 3 table and screenshots—before treating the issue.
|
||||
|
||||
## Checklist
|
||||
|
||||
```
|
||||
□ Same time range on both dashboards
|
||||
□ Confirmed no direct-to-provider traffic for those models
|
||||
□ Compared: requests, input tokens, output tokens, cache tokens
|
||||
□ Noted cache reporting differences (OpenAI vs Anthropic, and so on)
|
||||
□ If > ~10% delta on quantities → Path A: report with screenshots, endpoints, model names
|
||||
□ If quantities match → Path B: verify formula (B1) and model map pricing (B2)
|
||||
□ If neither path fits → open a GitHub issue.
|
||||
```
|
||||
|
||||
## See also
|
||||
|
||||
- [Spend tracking](../proxy/cost_tracking)
|
||||
- [Sync model pricing from GitHub](../proxy/sync_models_github)
|
||||
BIN
docs/my-website/img/release_notes/guardrail_fallbacks.png
Normal file
BIN
docs/my-website/img/release_notes/guardrail_fallbacks.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 435 KiB |
7
docs/my-website/package-lock.json
generated
7
docs/my-website/package-lock.json
generated
|
|
@ -20403,6 +20403,13 @@
|
|||
"url": "https://opencollective.com/webpack"
|
||||
}
|
||||
},
|
||||
"node_modules/search-insights": {
|
||||
"version": "2.17.3",
|
||||
"resolved": "https://registry.npmjs.org/search-insights/-/search-insights-2.17.3.tgz",
|
||||
"integrity": "sha512-RQPdCYTa8A68uM2jwxoY842xDhvx3E5LFL1LxvxCNMev4o5mLuokczhzjAgGwUZBAmOKZknArSxLKmXtIi2AxQ==",
|
||||
"license": "MIT",
|
||||
"peer": true
|
||||
},
|
||||
"node_modules/section-matter": {
|
||||
"version": "1.0.0",
|
||||
"resolved": "https://registry.npmjs.org/section-matter/-/section-matter-1.0.0.tgz",
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
---
|
||||
title: "[Preview] v1.83.3.rc.1 - Introducing MCP Skills Marketplace"
|
||||
slug: "v1-83-3-rc-1"
|
||||
title: "v1.83.3-stable - MCP Toolsets & Skills Marketplace"
|
||||
slug: "v1-83-3-stable"
|
||||
date: 2026-04-04T00:00:00
|
||||
authors:
|
||||
- name: Krrish Dholakia
|
||||
|
|
@ -14,7 +14,7 @@ authors:
|
|||
- name: Ryan Crabbe
|
||||
title: Full Stack Engineer, LiteLLM
|
||||
url: https://www.linkedin.com/in/ryan-crabbe-0b9687214
|
||||
image_url: https://media.licdn.com/dms/image/v2/D5603AQHt1t9Z4BJ6Gw/profile-displayphoto-shrink_400_400/profile-displayphoto-shrink_400_400/0/1724453682340?e=1772064000&v=beta&t=VXdmr13rsNB05wyA2F1TENOB5UuDHUZ0FCHTolNyR5M
|
||||
image_url: https://github.com/ryan-crabbe.png
|
||||
- name: Yuneng Jiang
|
||||
title: Senior Full Stack Engineer, LiteLLM
|
||||
url: https://www.linkedin.com/in/yuneng-david-jiang-455676139/
|
||||
|
|
@ -38,14 +38,14 @@ import TabItem from '@theme/TabItem';
|
|||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
docker.litellm.ai/berriai/litellm:main-v1.83.3.rc.1
|
||||
docker.litellm.ai/berriai/litellm:main-v1.83.3-stable
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="pip" label="Pip">
|
||||
|
||||
```bash
|
||||
pip install litellm==1.83.3rc1
|
||||
pip install litellm==1.83.3
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
|
@ -71,8 +71,12 @@ The Skills Marketplace gives teams a self-hosted catalog for discovering, instal
|
|||
|
||||
### Guardrail Fallbacks
|
||||
|
||||

|
||||
|
||||
Guardrail pipelines now support an optional `on_error` behavior. When a guardrail check fails or errors out, you can configure the pipeline to fall back gracefully — logging the failure and continuing the request — instead of returning a hard 500 to the caller. This is especially useful for non-critical guardrails where availability matters more than enforcement.
|
||||
|
||||
[Get Started](../../docs/proxy/guardrails/policy_flow_builder)
|
||||
|
||||
### Team Bring Your Own Guardrails
|
||||
|
||||
Teams can now attach guardrails directly from the team management UI. Admins configure available guardrails at the project or proxy level, and individual teams select which ones apply to their traffic — no config file changes or proxy restarts needed. This also ships with project-level guardrail support in the project create/edit flows.
|
||||
|
|
@ -84,67 +88,234 @@ MCP Toolsets let AI platform admins create curated subsets of tools from one or
|
|||

|
||||
|
||||
[Get Started](../../docs/mcp)
|
||||
|
||||
---
|
||||
|
||||
## New Models / Updated Models
|
||||
|
||||
#### New Model Support
|
||||
#### New Model Support (60 new models)
|
||||
|
||||
| Provider | Model | Context Window | Input ($/1M tokens) | Output ($/1M tokens) | Features |
|
||||
| -------- | ----- | -------------- | ------------------- | -------------------- | -------- |
|
||||
| Brave Search | `brave/search` | - | - | - | Search tool integration metadata in cost map ([PR #25042](https://github.com/BerriAI/litellm/pull/25042)) |
|
||||
| AWS Bedrock | `nvidia.nemotron-super-3-120b` | 256K | Added | Added | Chat completions, function calling, system messages ([PR #24588](https://github.com/BerriAI/litellm/pull/24588)) |
|
||||
| OCI GenAI | Multiple new chat + embedding entries | Varies | Updated | Updated | Expanded chat + embedding model catalog |
|
||||
| OpenAI | `gpt-5.4-mini` | 272K | $0.75 | $4.50 | Chat, cache read, flex/batch/priority tiers |
|
||||
| OpenAI | `gpt-5.4-nano` | 272K | $0.20 | - | Chat, flex/batch tiers |
|
||||
| OpenAI | `gpt-4-0314` | 8K | $30.00 | $60.00 | Re-added legacy entry (deprecation 2026-03-26) |
|
||||
| Azure OpenAI | `azure/gpt-5.4-mini` | 1.05M | $0.75 | $4.50 | Chat completions, cache read |
|
||||
| Azure OpenAI | `azure/gpt-5.4-nano` | - | - | - | Chat completions |
|
||||
| AWS Bedrock | `us.amazon.nova-canvas-v1:0` | 2.6K | - | $0.06 / image | Nova Canvas image edit support |
|
||||
| AWS Bedrock | `nvidia.nemotron-super-3-120b` | 256K | $0.15 | $0.65 | Function calling, reasoning, system messages |
|
||||
| AWS Bedrock | `minimax.minimax-m2.5` (12 regions) | 1M | $0.30 | $1.20 | Function calling, reasoning, system messages |
|
||||
| AWS Bedrock | `zai.glm-5` | 200K | $1.00 | $3.20 | Function calling, reasoning |
|
||||
| AWS Bedrock | `bedrock/us-gov-{east,west}-1/anthropic.claude-haiku-4-5-20251001-v1:0` | 200K | $1.20 | $6.00 | GovCloud Claude Haiku 4.5 |
|
||||
| Vertex AI | `vertex_ai/claude-haiku-4-5` | 200K | $1.00 | $5.00 | Chat, cache creation/read |
|
||||
| Gemini | `gemini-3.1-flash-live-preview` / `gemini/gemini-3.1-flash-live-preview` | 131K | $0.75 | - | Live audio/video/image/text |
|
||||
| Gemini | `gemini/lyria-3-pro-preview`, `gemini/lyria-3-clip-preview` | 131K | - | - | Music generation preview |
|
||||
| xAI | `xai/grok-4.20-beta-0309-reasoning` | 2M | $2.00 | $6.00 | Function calling, reasoning |
|
||||
| xAI | `xai/grok-4.20-beta-0309-non-reasoning` | 2M | - | - | Function calling |
|
||||
| xAI | `xai/grok-4.20-multi-agent-beta-0309` | 2M | - | - | Multi-agent preview |
|
||||
| OCI GenAI | `oci/cohere.command-a-reasoning-08-2025`, `oci/cohere.command-a-vision-07-2025`, `oci/cohere.command-a-translate-08-2025`, `oci/cohere.command-r-08-2024`, `oci/cohere.command-r-plus-08-2024` | 256K | $1.56 | $1.56 | Cohere chat family on OCI |
|
||||
| OCI GenAI | `oci/meta.llama-3.1-70b-instruct`, `oci/meta.llama-3.2-11b-vision-instruct`, `oci/meta.llama-3.3-70b-instruct-fp8-dynamic` | Varies | Varies | Varies | Llama chat family on OCI |
|
||||
| OCI GenAI | `oci/xai.grok-4-fast`, `oci/xai.grok-4.1-fast`, `oci/xai.grok-4.20`, `oci/xai.grok-4.20-multi-agent`, `oci/xai.grok-code-fast-1` | 131K | $3.00 | $15.00 | Grok family on OCI |
|
||||
| OCI GenAI | `oci/google.gemini-2.5-pro`, `oci/google.gemini-2.5-flash`, `oci/google.gemini-2.5-flash-lite` | 1M+ | $1.25 | $10.00 | Gemini family on OCI |
|
||||
| OCI GenAI | `oci/cohere.embed-english-v3.0`, `oci/cohere.embed-english-light-v3.0`, `oci/cohere.embed-multilingual-v3.0`, `oci/cohere.embed-multilingual-light-v3.0`, `oci/cohere.embed-english-image-v3.0`, `oci/cohere.embed-english-light-image-v3.0`, `oci/cohere.embed-multilingual-light-image-v3.0`, `oci/cohere.embed-v4.0` | Varies | Varies | - | Embeddings on OCI |
|
||||
| Volcengine | `volcengine/doubao-seed-2-0-pro-260215`, `doubao-seed-2-0-lite-260215`, `doubao-seed-2-0-mini-260215`, `doubao-seed-2-0-code-preview-260215` | 256K | - | - | Doubao Seed 2.0 family |
|
||||
|
||||
#### Features
|
||||
|
||||
- **[AWS Bedrock](../../docs/providers/bedrock)**
|
||||
- Add Nova Canvas image edit support - [PR #25110](https://github.com/BerriAI/litellm/pull/25110), [PR #24869](https://github.com/BerriAI/litellm/pull/24869)
|
||||
- Improve cache usage exposure for Claude-compatible streaming paths - [PR #25110](https://github.com/BerriAI/litellm/pull/25110), [PR #24850](https://github.com/BerriAI/litellm/pull/24850)
|
||||
- Bedrock model catalog updates - [PR #24645](https://github.com/BerriAI/litellm/pull/24645)
|
||||
- Add Nova Canvas image edit support - [PR #24869](https://github.com/BerriAI/litellm/pull/24869), [PR #25110](https://github.com/BerriAI/litellm/pull/25110)
|
||||
- Add `nvidia.nemotron-super-3-120b` entries and Bedrock model catalog updates - [PR #24588](https://github.com/BerriAI/litellm/pull/24588), [PR #24645](https://github.com/BerriAI/litellm/pull/24645)
|
||||
- Add MiniMax M2.5 cross-region entries - cost map additions
|
||||
- Add `zai.glm-5` pricing entry
|
||||
- Improve cache usage exposure for Claude-compatible streaming paths - [PR #24850](https://github.com/BerriAI/litellm/pull/24850)
|
||||
- Structured output cost tracking fix for Bedrock JSON mode - [PR #23794](https://github.com/BerriAI/litellm/pull/23794)
|
||||
- Preserve JSON-RPC envelope for AgentCore A2A-native agents - [PR #25092](https://github.com/BerriAI/litellm/pull/25092)
|
||||
- Fix Bedrock Anthropic file/document handling - [PR #25047](https://github.com/BerriAI/litellm/pull/25047), [PR #25050](https://github.com/BerriAI/litellm/pull/25050)
|
||||
- Fix Bedrock count-tokens with custom endpoint - [PR #24199](https://github.com/BerriAI/litellm/pull/24199)
|
||||
|
||||
- **[OCI GenAI](../../docs/providers/oci)**
|
||||
- Add native embeddings support + expanded model catalog - [PR #25151](https://github.com/BerriAI/litellm/pull/25151), [PR #24887](https://github.com/BerriAI/litellm/pull/24887)
|
||||
- **[Fireworks AI](../../docs/providers/fireworks_ai)**
|
||||
- Skip `#transform=inline` for base64 data URLs - [PR #23818](https://github.com/BerriAI/litellm/pull/23818)
|
||||
|
||||
- **[DeepInfra](../../docs/providers/deepinfra)**
|
||||
- Mock DeepInfra completion tests to avoid real API calls - [PR #24805](https://github.com/BerriAI/litellm/pull/24805)
|
||||
|
||||
- **[WatsonX](../../docs/providers/watsonx)**
|
||||
- Fix WatsonX tests failing in CI due to missing env vars - [PR #24814](https://github.com/BerriAI/litellm/pull/24814)
|
||||
|
||||
- **[Snowflake Cortex](../../docs/providers/snowflake)**
|
||||
- Move Snowflake mocked tests to unit test directory - [PR #24822](https://github.com/BerriAI/litellm/pull/24822)
|
||||
|
||||
- **[Anthropic](../../docs/providers/anthropic)**
|
||||
- Surface Anthropic tool results in Responses API - [PR #23784](https://github.com/BerriAI/litellm/pull/23784)
|
||||
- Auth token and custom `api_base` support - [PR #24140](https://github.com/BerriAI/litellm/pull/24140)
|
||||
- Preserve beta header order - [PR #23715](https://github.com/BerriAI/litellm/pull/23715)
|
||||
- Cache-control support for Anthropic document/file message blocks - [PR #23906](https://github.com/BerriAI/litellm/pull/23906), [PR #23911](https://github.com/BerriAI/litellm/pull/23911)
|
||||
- Map Anthropic refusal finish_reason - [PR #23899](https://github.com/BerriAI/litellm/pull/23899)
|
||||
- Cache-control on tool config - [PR #24076](https://github.com/BerriAI/litellm/pull/24076)
|
||||
- Remove 200K pricing entries for Opus/Sonnet 4.6 - [PR #24689](https://github.com/BerriAI/litellm/pull/24689)
|
||||
|
||||
- **[OpenAI](../../docs/providers/openai)**
|
||||
- Add `gpt-5.4-mini` / `gpt-5.4-nano` with flex/batch/priority tiers - [PR #23958](https://github.com/BerriAI/litellm/pull/23958)
|
||||
- Restore `gpt-4-0314` cost entry with deprecation metadata - [PR #23753](https://github.com/BerriAI/litellm/pull/23753)
|
||||
- OpenAI reasoning items in chat completions - [PR #24690](https://github.com/BerriAI/litellm/pull/24690)
|
||||
|
||||
- **[Google Vertex AI](../../docs/providers/vertex)**
|
||||
- Add unversioned Claude Haiku pricing entry to ensure accurate spend accounting - [PR #25151](https://github.com/BerriAI/litellm/pull/25151)
|
||||
- Add `vertex_ai/claude-haiku-4-5` pricing entry - [PR #25151](https://github.com/BerriAI/litellm/pull/25151)
|
||||
- Vertex `count_tokens` location override - [PR #23907](https://github.com/BerriAI/litellm/pull/23907)
|
||||
- Vertex cancel batch endpoint - [PR #23957](https://github.com/BerriAI/litellm/pull/23957)
|
||||
- Vertex PAYGO tutorial - [PR #24009](https://github.com/BerriAI/litellm/pull/24009)
|
||||
- Fix Vertex AI batch - [PR #23718](https://github.com/BerriAI/litellm/pull/23718)
|
||||
- DeepSeek v3.2 Vertex region mapping - [PR #23864](https://github.com/BerriAI/litellm/pull/23864)
|
||||
|
||||
- **[Google Gemini](../../docs/providers/gemini)**
|
||||
- Add `gemini-3.1-flash-live-preview` model - [PR #24665](https://github.com/BerriAI/litellm/pull/24665)
|
||||
- Add Lyria 3 Pro / Clip preview entries + docs - [PR #24610](https://github.com/BerriAI/litellm/pull/24610)
|
||||
- Normalize Gemini retrieve-file URL - [PR #24662](https://github.com/BerriAI/litellm/pull/24662)
|
||||
- Gemini context caching with custom `api_base` - [PR #23928](https://github.com/BerriAI/litellm/pull/23928)
|
||||
- Strict `additional_properties` cleanup - [PR #24072](https://github.com/BerriAI/litellm/pull/24072)
|
||||
- Gemini context circulation - [PR #24073](https://github.com/BerriAI/litellm/pull/24073)
|
||||
|
||||
- **[Azure OpenAI](../../docs/providers/azure)**
|
||||
- Add `azure/gpt-5.4-mini` / `azure/gpt-5.4-nano` pricing - model catalog
|
||||
- Bump proxy Azure API version - [PR #24120](https://github.com/BerriAI/litellm/pull/24120)
|
||||
- Azure fine-tuning fixes - [PR #24687](https://github.com/BerriAI/litellm/pull/24687)
|
||||
- Azure gpt-5.4 Responses API routing fix - [PR #23926](https://github.com/BerriAI/litellm/pull/23926)
|
||||
- Azure AI annotations - [PR #23939](https://github.com/BerriAI/litellm/pull/23939)
|
||||
|
||||
- **[xAI](../../docs/providers/xai)**
|
||||
- Add Grok 4.20 reasoning / non-reasoning / multi-agent preview entries - cost map
|
||||
|
||||
- **[OCI GenAI](../../docs/providers/oci)**
|
||||
- Native embeddings support and expanded chat + embedding model catalog - [PR #24887](https://github.com/BerriAI/litellm/pull/24887), [PR #25151](https://github.com/BerriAI/litellm/pull/25151)
|
||||
|
||||
- **[Volcengine](../../docs/providers/volcengine)**
|
||||
- Add Doubao Seed 2.0 pro/lite/mini/code-preview entries - cost map
|
||||
|
||||
- **[Mistral](../../docs/providers/mistral)**
|
||||
- Fix Mistral diarize segments response - [PR #23925](https://github.com/BerriAI/litellm/pull/23925)
|
||||
|
||||
- **[OpenRouter](../../docs/providers/openrouter)**
|
||||
- Strip prefix on OpenRouter wildcard routing - [PR #24603](https://github.com/BerriAI/litellm/pull/24603)
|
||||
|
||||
- **[Deepgram](../../docs/providers/deepgram)**
|
||||
- Revert problematic cost-per-second change - [PR #24297](https://github.com/BerriAI/litellm/pull/24297)
|
||||
|
||||
- **[GitHub Copilot](../../docs/providers/github_copilot)**
|
||||
- Short-circuit web search when not supported by Copilot model - [PR #24143](https://github.com/BerriAI/litellm/pull/24143)
|
||||
|
||||
- **[Snowflake Cortex](../../docs/providers/snowflake)**
|
||||
- Test conflict resolution and reliability fixes - merges across release window
|
||||
|
||||
- **[Quora / Poe](../../docs/providers/poe)**
|
||||
- Fix missing content-part added event - [PR #24445](https://github.com/BerriAI/litellm/pull/24445)
|
||||
|
||||
### Bug Fixes
|
||||
|
||||
- **General**
|
||||
- Fix `gpt-5.4` pricing metadata - [PR #24748](https://github.com/BerriAI/litellm/pull/24748)
|
||||
- Fix gov pricing tests and Bedrock model test follow-ups - [PR #25022](https://github.com/BerriAI/litellm/pull/25022), [PR #24947](https://github.com/BerriAI/litellm/pull/24947), [PR #24931](https://github.com/BerriAI/litellm/pull/24931)
|
||||
- Fix gov pricing tests and Bedrock model test follow-ups - [PR #24931](https://github.com/BerriAI/litellm/pull/24931), [PR #24947](https://github.com/BerriAI/litellm/pull/24947), [PR #25022](https://github.com/BerriAI/litellm/pull/25022)
|
||||
- Fix thinking blocks null handling - [PR #24070](https://github.com/BerriAI/litellm/pull/24070)
|
||||
- Streaming tool-call finish reason with empty content - [PR #23895](https://github.com/BerriAI/litellm/pull/23895)
|
||||
- Ensure alternating roles in conversion paths - [PR #24015](https://github.com/BerriAI/litellm/pull/24015)
|
||||
- File → input_file mapping fix - [PR #23618](https://github.com/BerriAI/litellm/pull/23618)
|
||||
- File-search emulated alignment - [PR #23969](https://github.com/BerriAI/litellm/pull/23969)
|
||||
- Preserve final streaming attributes - [PR #23530](https://github.com/BerriAI/litellm/pull/23530)
|
||||
- Streaming metadata hidden params - [PR #24220](https://github.com/BerriAI/litellm/pull/24220)
|
||||
- Improve LLM repeated message detection performance - [PR #18120](https://github.com/BerriAI/litellm/pull/18120)
|
||||
|
||||
## LLM API Endpoints
|
||||
|
||||
#### Features
|
||||
|
||||
- **[A2A / MCP Gateway API (/a2a, /mcp)](../../docs/mcp)**
|
||||
- **[Responses API](../../docs/response_api)**
|
||||
- File Search support — Phase 1 native passthrough and Phase 2 emulated fallback for non-OpenAI models - [PR #23969](https://github.com/BerriAI/litellm/pull/23969)
|
||||
- Prompt management support for Responses API - [PR #23999](https://github.com/BerriAI/litellm/pull/23999)
|
||||
- Encrypted-content affinity across model versions - [PR #23854](https://github.com/BerriAI/litellm/pull/23854), [PR #24110](https://github.com/BerriAI/litellm/pull/24110)
|
||||
- Round-trip Responses API `reasoning_items` in chat completions - [PR #24690](https://github.com/BerriAI/litellm/pull/24690)
|
||||
- Emit `content_part.added` streaming event for non-OpenAI models - [PR #24445](https://github.com/BerriAI/litellm/pull/24445)
|
||||
- Surface Anthropic code execution results as `code_interpreter_call` - [PR #23784](https://github.com/BerriAI/litellm/pull/23784)
|
||||
- Preserve Anthropic `thinking.summary` when routing to OpenAI Responses API - [PR #21441](https://github.com/BerriAI/litellm/pull/21441)
|
||||
- Auto-route Azure `gpt-5.4+` tools + reasoning to Responses API - [PR #23926](https://github.com/BerriAI/litellm/pull/23926)
|
||||
- Preserve annotations in Azure AI Foundry Agents responses - [PR #23939](https://github.com/BerriAI/litellm/pull/23939)
|
||||
- API reference path routing updates - [PR #24155](https://github.com/BerriAI/litellm/pull/24155)
|
||||
- Map Chat Completion `file` type to Responses API `input_file` - [PR #23618](https://github.com/BerriAI/litellm/pull/23618)
|
||||
- Map `file_url` → `file_id` in Responses→Completions translation - [PR #24874](https://github.com/BerriAI/litellm/pull/24874)
|
||||
|
||||
- **[Batch API](../../docs/batches)**
|
||||
- Vertex AI batch cancel support - [PR #23957](https://github.com/BerriAI/litellm/pull/23957)
|
||||
|
||||
- **Token Counting**
|
||||
- Bedrock: respect `api_base` and `aws_bedrock_runtime_endpoint` - [PR #24199](https://github.com/BerriAI/litellm/pull/24199)
|
||||
- Vertex: respect `vertex_count_tokens_location` for Claude - [PR #23907](https://github.com/BerriAI/litellm/pull/23907)
|
||||
|
||||
- **[Audio / Transcription API](../../docs/audio_transcription)**
|
||||
- Mistral: preserve diarization segments in transcription response - [PR #23925](https://github.com/BerriAI/litellm/pull/23925)
|
||||
|
||||
- **[Embeddings API](../../docs/embedding/supported_embedding)**
|
||||
- Gemini: convert `task_type` to camelCase `taskType` for Gemini API - [PR #24191](https://github.com/BerriAI/litellm/pull/24191)
|
||||
|
||||
- **[Video Generation](../../docs/video_generation)**
|
||||
- New reusable video character endpoints (create / edit / extension / get) with router-first routing - [PR #23737](https://github.com/BerriAI/litellm/pull/23737)
|
||||
|
||||
- **[Search API](../../docs/search)**
|
||||
- Support self-hosted Firecrawl response format - [PR #24866](https://github.com/BerriAI/litellm/pull/24866)
|
||||
|
||||
- **[A2A / MCP Gateway API](../../docs/mcp)**
|
||||
- Preserve JSON-RPC envelope for AgentCore A2A-native agents - [PR #25092](https://github.com/BerriAI/litellm/pull/25092)
|
||||
- Bedrock Anthropic file/document handling fix from internal staging - [PR #25050](https://github.com/BerriAI/litellm/pull/25050), [PR #25047](https://github.com/BerriAI/litellm/pull/25047)
|
||||
|
||||
- **[Pass-Through Endpoints](../../docs/pass_through/intro)**
|
||||
- Support `ANTHROPIC_AUTH_TOKEN` / `ANTHROPIC_BASE_URL` env vars and custom `api_base` in experimental passthrough - [PR #24140](https://github.com/BerriAI/litellm/pull/24140)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- **[Search API (/search)](../../docs/search)**
|
||||
- Support self-hosted Firecrawl response format in search transforms - [PR #25110](https://github.com/BerriAI/litellm/pull/25110), [PR #24866](https://github.com/BerriAI/litellm/pull/24866)
|
||||
- **[Responses API](../../docs/response_api)**
|
||||
- Use real `request_data` in Responses API streaming fallback path - [PR #23910](https://github.com/BerriAI/litellm/pull/23910)
|
||||
- Fix Responses API cost calculation - [PR #24080](https://github.com/BerriAI/litellm/pull/24080)
|
||||
|
||||
- **[Pass-Through Endpoints](../../docs/pass_through/intro)**
|
||||
- Allow non-admin users to access pass-through subpath routes with auth - [PR #24079](https://github.com/BerriAI/litellm/pull/24079)
|
||||
- Prevent duplicate callback logs for pass-through endpoint failures - [PR #23509](https://github.com/BerriAI/litellm/pull/23509)
|
||||
|
||||
- **General**
|
||||
- Proxy-only failure call-type handling - [PR #24050](https://github.com/BerriAI/litellm/pull/24050)
|
||||
- Generic API model-group logging fix - [PR #24044](https://github.com/BerriAI/litellm/pull/24044)
|
||||
|
||||
## Management Endpoints / UI
|
||||
|
||||
#### Features
|
||||
|
||||
- **Virtual Keys**
|
||||
- Add substring search for `user_id` and `key_alias` on `/key/list` - [PR #24751](https://github.com/BerriAI/litellm/pull/24751), [PR #24746](https://github.com/BerriAI/litellm/pull/24746)
|
||||
- Wire `team_id` filter to key alias dropdown on Virtual Keys tab - [PR #25119](https://github.com/BerriAI/litellm/pull/25119), [PR #25114](https://github.com/BerriAI/litellm/pull/25114)
|
||||
- Allow hashed `token_id` in `/key/update` endpoint - [PR #24969](https://github.com/BerriAI/litellm/pull/24969)
|
||||
- Substring search for `user_id` and `key_alias` on `/key/list` - [PR #24746](https://github.com/BerriAI/litellm/pull/24746), [PR #24751](https://github.com/BerriAI/litellm/pull/24751)
|
||||
- Wire `team_id` filter to key alias dropdown - [PR #25114](https://github.com/BerriAI/litellm/pull/25114), [PR #25119](https://github.com/BerriAI/litellm/pull/25119)
|
||||
- Allow hashed `token_id` in `/key/update` - [PR #24969](https://github.com/BerriAI/litellm/pull/24969)
|
||||
- Enforce upper-bound key params on `/key/update` and bulk update hook paths - [PR #25103](https://github.com/BerriAI/litellm/pull/25103), [PR #25110](https://github.com/BerriAI/litellm/pull/25110)
|
||||
- Fix create-key tags dropdown - [PR #24273](https://github.com/BerriAI/litellm/pull/24273)
|
||||
- Fix key-update 404 - [PR #24063](https://github.com/BerriAI/litellm/pull/24063)
|
||||
- Fix key admin privilege escalation - [PR #23781](https://github.com/BerriAI/litellm/pull/23781)
|
||||
- Key-endpoint authentication hardening - [PR #23977](https://github.com/BerriAI/litellm/pull/23977)
|
||||
- Disable custom API keys flag - [PR #23812](https://github.com/BerriAI/litellm/pull/23812)
|
||||
- Skip alias revalidation on key update - [PR #23798](https://github.com/BerriAI/litellm/pull/23798)
|
||||
- Fix invalid keys for internal users - [PR #23795](https://github.com/BerriAI/litellm/pull/23795)
|
||||
- Distributed lock for scheduled key rotation job execution - [PR #23364](https://github.com/BerriAI/litellm/pull/23364), [PR #23834](https://github.com/BerriAI/litellm/pull/23834), [PR #25150](https://github.com/BerriAI/litellm/pull/25150)
|
||||
|
||||
- **Teams + Organizations**
|
||||
- Resolve access-group models/MCP servers/agents in team endpoints and UI - [PR #25119](https://github.com/BerriAI/litellm/pull/25119), [PR #25027](https://github.com/BerriAI/litellm/pull/25027)
|
||||
- Resolve access-group models / MCP servers / agents in team endpoints and UI - [PR #25027](https://github.com/BerriAI/litellm/pull/25027), [PR #25119](https://github.com/BerriAI/litellm/pull/25119)
|
||||
- Allow changing team organization from team settings - [PR #25095](https://github.com/BerriAI/litellm/pull/25095)
|
||||
- Add per-model rate limits to team edit/info views - [PR #25156](https://github.com/BerriAI/litellm/pull/25156), [PR #25144](https://github.com/BerriAI/litellm/pull/25144)
|
||||
- Per-model rate limits in team edit/info views - [PR #25144](https://github.com/BerriAI/litellm/pull/25144), [PR #25156](https://github.com/BerriAI/litellm/pull/25156)
|
||||
- Fix team model update 500 due to unsupported Prisma JSON path filter - [PR #25152](https://github.com/BerriAI/litellm/pull/25152)
|
||||
- Team model-group name routing fix - [PR #24688](https://github.com/BerriAI/litellm/pull/24688)
|
||||
- Modernize teams table - [PR #24189](https://github.com/BerriAI/litellm/pull/24189)
|
||||
- Team-member budget duration on create - [PR #23484](https://github.com/BerriAI/litellm/pull/23484)
|
||||
- Add missing `team_member_budget_duration` param to `new_team` docstring - [PR #24243](https://github.com/BerriAI/litellm/pull/24243)
|
||||
- Fix teams table refresh, infinite dropdown, and leftnav migration - [PR #24342](https://github.com/BerriAI/litellm/pull/24342)
|
||||
|
||||
- **Usage + Analytics**
|
||||
- Add paginated team search on usage page filters - [PR #25107](https://github.com/BerriAI/litellm/pull/25107)
|
||||
- Paginated team search on usage page filters - [PR #25107](https://github.com/BerriAI/litellm/pull/25107)
|
||||
- Use entity key for usage export display correctness - [PR #25153](https://github.com/BerriAI/litellm/pull/25153)
|
||||
- Aggregated activity entity breakdown - [PR #23471](https://github.com/BerriAI/litellm/pull/23471)
|
||||
- CSV export fixes - [PR #23819](https://github.com/BerriAI/litellm/pull/23819)
|
||||
- Audit log S3 export - [PR #23167](https://github.com/BerriAI/litellm/pull/23167)
|
||||
- Audit log export UI - [PR #24486](https://github.com/BerriAI/litellm/pull/24486)
|
||||
|
||||
- **Models + Providers**
|
||||
- Include access-group models in UI model listing - [PR #24743](https://github.com/BerriAI/litellm/pull/24743)
|
||||
|
|
@ -152,85 +323,200 @@ MCP Toolsets let AI platform admins create curated subsets of tools from one or
|
|||
- Do not inject `vector_store_ids: []` when editing a model - [PR #25133](https://github.com/BerriAI/litellm/pull/25133)
|
||||
|
||||
- **Guardrails UI**
|
||||
- Add project-level guardrails support in project create/edit flows - [PR #25100](https://github.com/BerriAI/litellm/pull/25100)
|
||||
- Project-level guardrails in project create/edit flows - [PR #25100](https://github.com/BerriAI/litellm/pull/25100)
|
||||
- Project-level guardrails support in the proxy - [PR #25087](https://github.com/BerriAI/litellm/pull/25087)
|
||||
- Allow adding team guardrails from the UI - [PR #25038](https://github.com/BerriAI/litellm/pull/25038)
|
||||
|
||||
- **UI Cleanup**
|
||||
- **MCP Toolsets UI**
|
||||
- New Toolsets tab for curated MCP tool subsets with scoped permissions - [PR #25155](https://github.com/BerriAI/litellm/pull/25155)
|
||||
|
||||
- **Auth / SSO**
|
||||
- Fix SSO return-to validation - [PR #24475](https://github.com/BerriAI/litellm/pull/24475)
|
||||
- Fix JWT role mappings - [PR #24701](https://github.com/BerriAI/litellm/pull/24701)
|
||||
- JWT `none` guard hardening - [PR #24706](https://github.com/BerriAI/litellm/pull/24706)
|
||||
- JWT to Virtual Key mapping docs - [PR #24882](https://github.com/BerriAI/litellm/pull/24882)
|
||||
- Remove login asterisks display - [PR #24318](https://github.com/BerriAI/litellm/pull/24318)
|
||||
- Copy `user_id` on click - [PR #24315](https://github.com/BerriAI/litellm/pull/24315)
|
||||
- Fix default user perms not synced with UI - [PR #23666](https://github.com/BerriAI/litellm/pull/23666)
|
||||
|
||||
- **UI Cleanup / Migration**
|
||||
- Migrate Tremor Text/Badge to antd Tag and native spans - [PR #24750](https://github.com/BerriAI/litellm/pull/24750)
|
||||
- Migrate default user settings to antd - [PR #23787](https://github.com/BerriAI/litellm/pull/23787)
|
||||
- Migrate route preview Tremor → antd - [PR #24485](https://github.com/BerriAI/litellm/pull/24485)
|
||||
- Migrate antd message to context API - [PR #24192](https://github.com/BerriAI/litellm/pull/24192)
|
||||
- Extract `useChatHistory` hook - [PR #24172](https://github.com/BerriAI/litellm/pull/24172)
|
||||
- Left-nav external icon - [PR #24069](https://github.com/BerriAI/litellm/pull/24069)
|
||||
- Vitest coverage for UI - [PR #24144](https://github.com/BerriAI/litellm/pull/24144)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- Fix logs page showing unfiltered results when backend filter returns zero rows - [PR #24745](https://github.com/BerriAI/litellm/pull/24745)
|
||||
- Enforce upperbound key params on `/key/update` and bulk update hook paths - [PR #25110](https://github.com/BerriAI/litellm/pull/25110), [PR #25103](https://github.com/BerriAI/litellm/pull/25103)
|
||||
- Fix team model update 500 due to unsupported Prisma JSON path filter - [PR #25152](https://github.com/BerriAI/litellm/pull/25152)
|
||||
- Fix UI logs filter - [PR #23792](https://github.com/BerriAI/litellm/pull/23792)
|
||||
- Fix edit budget flow - [PR #24711](https://github.com/BerriAI/litellm/pull/24711)
|
||||
- Fix bulk update - [PR #24708](https://github.com/BerriAI/litellm/pull/24708)
|
||||
- Fix user cache invalidation - [PR #24717](https://github.com/BerriAI/litellm/pull/24717)
|
||||
- Fix guardrail mode type crash - [PR #24035](https://github.com/BerriAI/litellm/pull/24035)
|
||||
- Sanitize proxy inputs - [PR #24624](https://github.com/BerriAI/litellm/pull/24624)
|
||||
|
||||
## AI Integrations
|
||||
|
||||
### Logging
|
||||
|
||||
- **[Langfuse](../../docs/proxy/logging#langfuse)**
|
||||
- Fix Langfuse usage metadata - [PR #24043](https://github.com/BerriAI/litellm/pull/24043)
|
||||
- Fix Langfuse OTEL traceparent propagation - [PR #24048](https://github.com/BerriAI/litellm/pull/24048)
|
||||
- Re-apply Langfuse key-leakage fix - [PR #22188](https://github.com/BerriAI/litellm/pull/22188), revert [PR #23868](https://github.com/BerriAI/litellm/pull/23868)
|
||||
|
||||
- **[Prometheus](../../docs/proxy/logging#prometheus)**
|
||||
- Organization budget metrics - [PR #24449](https://github.com/BerriAI/litellm/pull/24449)
|
||||
- Prometheus spend metadata - [PR #24434](https://github.com/BerriAI/litellm/pull/24434)
|
||||
|
||||
- **General**
|
||||
- Centralize logging kwarg updates via a single update function - [PR #23659](https://github.com/BerriAI/litellm/pull/23659)
|
||||
- Fix failure callbacks silently skipped when customLogger is not initialized - [PR #24826](https://github.com/BerriAI/litellm/pull/24826)
|
||||
- Eliminate race condition in streaming `guardrail_information` logging - [PR #24592](https://github.com/BerriAI/litellm/pull/24592)
|
||||
- Use actual `start_time` in failed request spend logs - [PR #24906](https://github.com/BerriAI/litellm/pull/24906)
|
||||
- Harden credential redaction + stop logging raw sensitive auth values - [PR #25151](https://github.com/BerriAI/litellm/pull/25151)
|
||||
- Harden credential redaction and stop logging raw sensitive auth values - [PR #25151](https://github.com/BerriAI/litellm/pull/25151), [PR #24305](https://github.com/BerriAI/litellm/pull/24305)
|
||||
- Filter metadata by `user_id` - [PR #24661](https://github.com/BerriAI/litellm/pull/24661)
|
||||
- Batch metrics improvements - [PR #24691](https://github.com/BerriAI/litellm/pull/24691)
|
||||
- Filter metadata hidden params in streaming - [PR #24220](https://github.com/BerriAI/litellm/pull/24220)
|
||||
- Shared aiohttp session auto-recovery - [PR #23808](https://github.com/BerriAI/litellm/pull/23808)
|
||||
- Deferred guardrail logging v2 - [PR #24135](https://github.com/BerriAI/litellm/pull/24135)
|
||||
|
||||
### Guardrails
|
||||
|
||||
- Add optional `on_error` for guardrail pipeline failures - [PR #25150](https://github.com/BerriAI/litellm/pull/25150), [PR #24831](https://github.com/BerriAI/litellm/pull/24831)
|
||||
- Register DynamoAI guardrail initializer and enum entry - [PR #23752](https://github.com/BerriAI/litellm/pull/23752)
|
||||
- Extract helper methods in guardrail handlers to fix PLR0915 - [PR #24802](https://github.com/BerriAI/litellm/pull/24802)
|
||||
- Add optional `on_error` fallback for guardrail pipeline failures - [PR #24831](https://github.com/BerriAI/litellm/pull/24831), [PR #25150](https://github.com/BerriAI/litellm/pull/25150)
|
||||
- Allow teams to attach/manage their own guardrails from team settings - [PR #25038](https://github.com/BerriAI/litellm/pull/25038)
|
||||
- Project-level guardrail config in create/edit flows - [PR #25100](https://github.com/BerriAI/litellm/pull/25100)
|
||||
- Return HTTP 400 (vs 500) for Model Armor streaming blocks - [PR #24693](https://github.com/BerriAI/litellm/pull/24693)
|
||||
- Deferred guardrail logging v2 - [PR #24135](https://github.com/BerriAI/litellm/pull/24135)
|
||||
- Eliminate race condition in streaming `guardrail_information` logging - [PR #24592](https://github.com/BerriAI/litellm/pull/24592)
|
||||
- Model-level guardrails on non-streaming post-call - [PR #23774](https://github.com/BerriAI/litellm/pull/23774)
|
||||
- Guardrail post-call logging fix - [PR #23910](https://github.com/BerriAI/litellm/pull/23910)
|
||||
- Missing guardrails docs - [PR #24083](https://github.com/BerriAI/litellm/pull/24083)
|
||||
|
||||
### Prompt Management
|
||||
|
||||
- Add environment + user tracking for prompts (`development/staging/production`) in CRUD + UI flows - [PR #25110](https://github.com/BerriAI/litellm/pull/25110), [PR #24855](https://github.com/BerriAI/litellm/pull/24855)
|
||||
- Environment + user tracking for prompts (`development/staging/production`) in CRUD + UI flows - [PR #24855](https://github.com/BerriAI/litellm/pull/24855), [PR #25110](https://github.com/BerriAI/litellm/pull/25110)
|
||||
- Prompt-to-responses integration - [PR #23999](https://github.com/BerriAI/litellm/pull/23999)
|
||||
|
||||
### Secret Managers
|
||||
|
||||
- No major new secret manager provider additions in this RC.
|
||||
- No new secret manager provider additions in this release.
|
||||
|
||||
## Spend Tracking, Budgets and Rate Limiting
|
||||
|
||||
- Enforce budget for models not directly present in the cost map - [PR #24949](https://github.com/BerriAI/litellm/pull/24949)
|
||||
- Add per-model rate limits in team settings/info UI - [PR #25144](https://github.com/BerriAI/litellm/pull/25144)
|
||||
- Per-model rate limits in team settings/info UI - [PR #25144](https://github.com/BerriAI/litellm/pull/25144), [PR #25156](https://github.com/BerriAI/litellm/pull/25156)
|
||||
- Prometheus organization budget metrics - [PR #24449](https://github.com/BerriAI/litellm/pull/24449)
|
||||
- Prometheus spend metadata - [PR #24434](https://github.com/BerriAI/litellm/pull/24434)
|
||||
- Fix unversioned Vertex Claude Haiku pricing entry to avoid `$0.00` accounting - [PR #25151](https://github.com/BerriAI/litellm/pull/25151)
|
||||
- Fix budget/spend counters - [PR #24682](https://github.com/BerriAI/litellm/pull/24682)
|
||||
- Project ID tracking in spend logs - [PR #24432](https://github.com/BerriAI/litellm/pull/24432)
|
||||
- Dynamic rate-limit pre-ratelimit background refresh - [PR #24106](https://github.com/BerriAI/litellm/pull/24106)
|
||||
- Point72 limits changes - [PR #24088](https://github.com/BerriAI/litellm/pull/24088)
|
||||
- Model-level affinity in router - [PR #24110](https://github.com/BerriAI/litellm/pull/24110)
|
||||
|
||||
## MCP Gateway
|
||||
|
||||
- Introduce **MCP Toolsets** with DB types, CRUD APIs, scoped permissions, and UI management tab - [PR #25155](https://github.com/BerriAI/litellm/pull/25155)
|
||||
- Resolve toolset names and enforce toolset access correctly in Responses API and streamable MCP paths - [PR #25155](https://github.com/BerriAI/litellm/pull/25155)
|
||||
- Switch toolset permission caching to shared cache path and improve cache invalidation behavior - [PR #25155](https://github.com/BerriAI/litellm/pull/25155)
|
||||
- Allow JWT auth for `/v1/mcp/server/*` sub-paths - [PR #25113](https://github.com/BerriAI/litellm/pull/25113), [PR #24698](https://github.com/BerriAI/litellm/pull/24698)
|
||||
- Allow JWT auth for `/v1/mcp/server/*` sub-paths - [PR #24698](https://github.com/BerriAI/litellm/pull/24698), [PR #25113](https://github.com/BerriAI/litellm/pull/25113)
|
||||
- Add STS AssumeRole support for MCP SigV4 auth - [PR #25151](https://github.com/BerriAI/litellm/pull/25151)
|
||||
- Add tag query fix + MCP metadata support cherry-pick - [PR #25145](https://github.com/BerriAI/litellm/pull/25145)
|
||||
- Tag query fix + MCP metadata support cherry-pick - [PR #25145](https://github.com/BerriAI/litellm/pull/25145)
|
||||
- MCP REST M2M OAuth2 flow - [PR #23468](https://github.com/BerriAI/litellm/pull/23468)
|
||||
- Upgrade MCP SDK to 1.26.0 - [PR #24179](https://github.com/BerriAI/litellm/pull/24179)
|
||||
- Restore MCP server fields dropped by schema sync migration - [PR #24078](https://github.com/BerriAI/litellm/pull/24078)
|
||||
|
||||
## Performance / Loadbalancing / Reliability improvements
|
||||
|
||||
- Integrate router health-check failures with cooldown behavior and transient 429/408 handling - [PR #25150](https://github.com/BerriAI/litellm/pull/25150), [PR #24988](https://github.com/BerriAI/litellm/pull/24988)
|
||||
- Add distributed lock for key rotation job execution - [PR #25150](https://github.com/BerriAI/litellm/pull/25150), [PR #23364](https://github.com/BerriAI/litellm/pull/23364), [PR #23834](https://github.com/BerriAI/litellm/pull/23834)
|
||||
- Improve team routing reliability with deterministic grouping, isolation fixes, stale alias controls, and order-based fallback - [PR #25154](https://github.com/BerriAI/litellm/pull/25154), [PR #25148](https://github.com/BerriAI/litellm/pull/25148)
|
||||
- Regenerate GCP IAM token per async Redis cluster connection (fix token TTL failures) - [PR #25155](https://github.com/BerriAI/litellm/pull/25155), [PR #24426](https://github.com/BerriAI/litellm/pull/24426)
|
||||
- Restore MCP server fields dropped by schema sync migration - [PR #24078](https://github.com/BerriAI/litellm/pull/24078)
|
||||
- Add control plane for multi-proxy worker management - [PR #24217](https://github.com/BerriAI/litellm/pull/24217)
|
||||
- Make DB migration failure exit opt-in via `--enforce_prisma_migration_check` - [PR #23675](https://github.com/BerriAI/litellm/pull/23675)
|
||||
- Return the picked model (not a comma-separated list) when batch completions is used - [PR #24753](https://github.com/BerriAI/litellm/pull/24753)
|
||||
- Fix mypy type errors in Responses transformation, spend tracking, and PagerDuty - [PR #24803](https://github.com/BerriAI/litellm/pull/24803)
|
||||
- Fix router code coverage CI failure for health check filter tests - [PR #24812](https://github.com/BerriAI/litellm/pull/24812)
|
||||
- Integrate router health-check failures with cooldown behavior and transient 429/408 handling - [PR #24988](https://github.com/BerriAI/litellm/pull/24988), [PR #25150](https://github.com/BerriAI/litellm/pull/25150)
|
||||
- Add distributed lock for key rotation job execution - [PR #23364](https://github.com/BerriAI/litellm/pull/23364), [PR #23834](https://github.com/BerriAI/litellm/pull/23834), [PR #25150](https://github.com/BerriAI/litellm/pull/25150)
|
||||
- Improve team routing reliability with deterministic grouping, isolation fixes, stale alias controls, and order-based fallback - [PR #25148](https://github.com/BerriAI/litellm/pull/25148), [PR #25154](https://github.com/BerriAI/litellm/pull/25154)
|
||||
- Regenerate GCP IAM token per async Redis cluster connection (fix token TTL failures) - [PR #24426](https://github.com/BerriAI/litellm/pull/24426), [PR #25155](https://github.com/BerriAI/litellm/pull/25155)
|
||||
- Proxy server reliability hardening with bounded queue usage - [PR #25155](https://github.com/BerriAI/litellm/pull/25155)
|
||||
- Auto schema sync on startup - [PR #24705](https://github.com/BerriAI/litellm/pull/24705)
|
||||
- Kill orphaned Prisma engine on reconnect - [PR #24149](https://github.com/BerriAI/litellm/pull/24149)
|
||||
- Use dynamic DB URL - [PR #24827](https://github.com/BerriAI/litellm/pull/24827)
|
||||
- Migration corrections - [PR #24105](https://github.com/BerriAI/litellm/pull/24105)
|
||||
|
||||
## Documentation Updates
|
||||
|
||||
- Improve HA control plane diagram clarity + mobile rendering updates - [PR #24747](https://github.com/BerriAI/litellm/pull/24747)
|
||||
- MCP zero trust auth guide - [PR #23918](https://github.com/BerriAI/litellm/pull/23918)
|
||||
- Week 1 onboarding checklist - [PR #25083](https://github.com/BerriAI/litellm/pull/25083)
|
||||
- Remove `NLP_CLOUD_API_KEY` requirement from `test_exceptions` - [PR #24756](https://github.com/BerriAI/litellm/pull/24756)
|
||||
- Update `gemini-2.0-flash` to `gemini-2.5-flash` in `test_gemini` - [PR #24817](https://github.com/BerriAI/litellm/pull/24817)
|
||||
- HA control-plane diagram clarity + mobile rendering updates - [PR #24747](https://github.com/BerriAI/litellm/pull/24747)
|
||||
- Document `default_team_params` in config reference and examples - [PR #25032](https://github.com/BerriAI/litellm/pull/25032)
|
||||
- Add JWT to Virtual Key mapping guide - [PR #24882](https://github.com/BerriAI/litellm/pull/24882)
|
||||
- Add MCP Toolsets docs and sidebar updates - [PR #25155](https://github.com/BerriAI/litellm/pull/25155)
|
||||
- JWT to Virtual Key mapping guide - [PR #24882](https://github.com/BerriAI/litellm/pull/24882)
|
||||
- MCP Toolsets docs and sidebar updates - [PR #25155](https://github.com/BerriAI/litellm/pull/25155)
|
||||
- Security docs updates and April hardening blog - [PR #24867](https://github.com/BerriAI/litellm/pull/24867), [PR #24868](https://github.com/BerriAI/litellm/pull/24868), [PR #24871](https://github.com/BerriAI/litellm/pull/24871), [PR #25102](https://github.com/BerriAI/litellm/pull/25102)
|
||||
- General docs cleanup + townhall announcement updates - [PR #24839](https://github.com/BerriAI/litellm/pull/24839), [PR #25026](https://github.com/BerriAI/litellm/pull/25026), [PR #25021](https://github.com/BerriAI/litellm/pull/25021)
|
||||
- Security incident blog - [PR #24537](https://github.com/BerriAI/litellm/pull/24537)
|
||||
- Security townhall blog - [PR #24692](https://github.com/BerriAI/litellm/pull/24692)
|
||||
- WebRTC blog - [PR #23547](https://github.com/BerriAI/litellm/pull/23547)
|
||||
- Vanta announcement - [PR #24800](https://github.com/BerriAI/litellm/pull/24800)
|
||||
- Prompt caching Gemini support docs - [PR #24222](https://github.com/BerriAI/litellm/pull/24222)
|
||||
- OpenCode / reasoningSummary docs - [PR #24468](https://github.com/BerriAI/litellm/pull/24468)
|
||||
- Thinking summary docs - [PR #22823](https://github.com/BerriAI/litellm/pull/22823)
|
||||
- v0 docs contributions - [PR #24023](https://github.com/BerriAI/litellm/pull/24023)
|
||||
- Blog posts RSS update - [PR #23791](https://github.com/BerriAI/litellm/pull/23791)
|
||||
- General docs cleanup + townhall announcements - [PR #24839](https://github.com/BerriAI/litellm/pull/24839), [PR #25021](https://github.com/BerriAI/litellm/pull/25021), [PR #25026](https://github.com/BerriAI/litellm/pull/25026)
|
||||
|
||||
## Infrastructure / Security Notes
|
||||
|
||||
- Optimize CI pipeline - [PR #23721](https://github.com/BerriAI/litellm/pull/23721)
|
||||
- Add zizmor to CI/CD - [PR #24663](https://github.com/BerriAI/litellm/pull/24663)
|
||||
- Remove `.claude/settings.json` and block re-adding via semgrep - [PR #24584](https://github.com/BerriAI/litellm/pull/24584)
|
||||
- Harden npm and Docker supply chain workflows and release pipeline checks - [PR #24838](https://github.com/BerriAI/litellm/pull/24838), [PR #24877](https://github.com/BerriAI/litellm/pull/24877), [PR #24881](https://github.com/BerriAI/litellm/pull/24881), [PR #24905](https://github.com/BerriAI/litellm/pull/24905), [PR #24951](https://github.com/BerriAI/litellm/pull/24951), [PR #25023](https://github.com/BerriAI/litellm/pull/25023), [PR #25034](https://github.com/BerriAI/litellm/pull/25034), [PR #25036](https://github.com/BerriAI/litellm/pull/25036), [PR #25037](https://github.com/BerriAI/litellm/pull/25037), [PR #25136](https://github.com/BerriAI/litellm/pull/25136), [PR #25158](https://github.com/BerriAI/litellm/pull/25158)
|
||||
- Resolve CodeQL/security workflow issues and fix broken action SHA references - [PR #24880](https://github.com/BerriAI/litellm/pull/24880), [PR #24815](https://github.com/BerriAI/litellm/pull/24815)
|
||||
- Re-add Codecov reporting in GHA matrix workflows - [PR #24804](https://github.com/BerriAI/litellm/pull/24804)
|
||||
- Fix(docker): load enterprise hooks in non-root runtime image - [PR #24917](https://github.com/BerriAI/litellm/pull/24917)
|
||||
- Apply Black formatting to 14 files - [PR #24532](https://github.com/BerriAI/litellm/pull/24532)
|
||||
- Resolve CodeQL/security workflow issues and fix broken action SHA references - [PR #24815](https://github.com/BerriAI/litellm/pull/24815), [PR #24880](https://github.com/BerriAI/litellm/pull/24880), [PR #24697](https://github.com/BerriAI/litellm/pull/24697)
|
||||
- Pin axios and tool versions - [PR #24829](https://github.com/BerriAI/litellm/pull/24829), [PR #24594](https://github.com/BerriAI/litellm/pull/24594), [PR #24607](https://github.com/BerriAI/litellm/pull/24607), [PR #24525](https://github.com/BerriAI/litellm/pull/24525), [PR #24696](https://github.com/BerriAI/litellm/pull/24696)
|
||||
- Re-add Codecov reporting in GHA matrix workflows - [PR #24804](https://github.com/BerriAI/litellm/pull/24804), [PR #24815](https://github.com/BerriAI/litellm/pull/24815)
|
||||
- Fix(docker): load enterprise hooks in non-root runtime image - [PR #24917](https://github.com/BerriAI/litellm/pull/24917), [PR #25037](https://github.com/BerriAI/litellm/pull/25037)
|
||||
- OSSF scorecard workflow - [PR #24792](https://github.com/BerriAI/litellm/pull/24792)
|
||||
- Skip scheduled workflows on forks - [PR #24460](https://github.com/BerriAI/litellm/pull/24460)
|
||||
- CI/CD improvements - [PR #24839](https://github.com/BerriAI/litellm/pull/24839), [PR #24837](https://github.com/BerriAI/litellm/pull/24837), [PR #24740](https://github.com/BerriAI/litellm/pull/24740), [PR #24741](https://github.com/BerriAI/litellm/pull/24741), [PR #24742](https://github.com/BerriAI/litellm/pull/24742), [PR #24754](https://github.com/BerriAI/litellm/pull/24754)
|
||||
- Remove neon CLI dependency - [PR #24951](https://github.com/BerriAI/litellm/pull/24951)
|
||||
- Workflow deletions - [PR #24541](https://github.com/BerriAI/litellm/pull/24541)
|
||||
- Publish to PyPI migration - [PR #24654](https://github.com/BerriAI/litellm/pull/24654)
|
||||
- Poetry lock / content-hash checks - [PR #24082](https://github.com/BerriAI/litellm/pull/24082), [PR #24159](https://github.com/BerriAI/litellm/pull/24159)
|
||||
- Apply Black formatting to 14 files - [PR #24532](https://github.com/BerriAI/litellm/pull/24532), [PR #24092](https://github.com/BerriAI/litellm/pull/24092), [PR #24153](https://github.com/BerriAI/litellm/pull/24153), [PR #24167](https://github.com/BerriAI/litellm/pull/24167), [PR #24173](https://github.com/BerriAI/litellm/pull/24173), [PR #24187](https://github.com/BerriAI/litellm/pull/24187)
|
||||
- Fix lint issues - [PR #24932](https://github.com/BerriAI/litellm/pull/24932)
|
||||
- Version bump to 1.83.0 - [PR #24840](https://github.com/BerriAI/litellm/pull/24840)
|
||||
- Test cleanup and reliability fixes - [PR #24755](https://github.com/BerriAI/litellm/pull/24755), [PR #24820](https://github.com/BerriAI/litellm/pull/24820), [PR #24824](https://github.com/BerriAI/litellm/pull/24824), [PR #24258](https://github.com/BerriAI/litellm/pull/24258)
|
||||
- License key environment handling - [PR #24168](https://github.com/BerriAI/litellm/pull/24168)
|
||||
- Remove phone numbers from repo - [PR #24587](https://github.com/BerriAI/litellm/pull/24587)
|
||||
|
||||
## New Contributors
|
||||
|
||||
* @voidborne-d made their first contribution in https://github.com/BerriAI/litellm/pull/23808
|
||||
* @vanhtuan0409 made their first contribution in https://github.com/BerriAI/litellm/pull/24078
|
||||
* @devin-petersohn made their first contribution in https://github.com/BerriAI/litellm/pull/24140
|
||||
* @benlangfeld made their first contribution in https://github.com/BerriAI/litellm/pull/24413
|
||||
* @J-Byron made their first contribution in https://github.com/BerriAI/litellm/pull/24449
|
||||
* @jaydns made their first contribution in https://github.com/BerriAI/litellm/pull/24823
|
||||
* @stuxf made their first contribution in https://github.com/BerriAI/litellm/pull/24838
|
||||
* @clfhhc made their first contribution in https://github.com/BerriAI/litellm/pull/24932
|
||||
|
||||
**Full Changelog**: https://github.com/BerriAI/litellm/compare/v1.83.0-nightly...v1.83.3.rc.1
|
||||
**Full Changelog**: https://github.com/BerriAI/litellm/compare/v1.82.3-stable...v1.83.3-stable
|
||||
|
||||
---
|
||||
|
||||
## 04/04/2026
|
||||
|
||||
* New Models / Updated Models: 59
|
||||
* LLM API Endpoints: 28
|
||||
* Management Endpoints / UI: 61
|
||||
* Logging / Guardrail / Prompt Management Integrations: 30
|
||||
* Spend Tracking, Budgets and Rate Limiting: 11
|
||||
* MCP Gateway: 8
|
||||
* Performance / Loadbalancing / Reliability improvements: 17
|
||||
* Documentation Updates: 24
|
||||
* Infrastructure / Security: 50
|
||||
|
|
|
|||
223
docs/my-website/release_notes/v1.83.7.rc.1/index.md
Normal file
223
docs/my-website/release_notes/v1.83.7.rc.1/index.md
Normal file
|
|
@ -0,0 +1,223 @@
|
|||
---
|
||||
title: "[Preview] v1.83.7.rc.1 - Per-User MCP OAuth, Team Spend Logs RBAC"
|
||||
slug: "v1-83-7-rc-1"
|
||||
date: 2026-04-12T00:00:00
|
||||
authors:
|
||||
- name: Krrish Dholakia
|
||||
title: CEO, LiteLLM
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: CTO, LiteLLM
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
- name: Ryan Crabbe
|
||||
title: Full Stack Engineer, LiteLLM
|
||||
url: https://www.linkedin.com/in/ryan-crabbe-0b9687214
|
||||
image_url: https://github.com/ryan-crabbe.png
|
||||
- name: Yuneng Jiang
|
||||
title: Senior Full Stack Engineer, LiteLLM
|
||||
url: https://www.linkedin.com/in/yuneng-david-jiang-455676139/
|
||||
image_url: https://avatars.githubusercontent.com/u/171294688?v=4
|
||||
- name: Shivam Rawat
|
||||
title: Forward Deployed Engineer, LiteLLM
|
||||
url: https://linkedin.com/in/shivam-rawat-482937318
|
||||
image_url: https://github.com/shivamrawat1.png
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
## Deploy this version
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="docker" label="Docker">
|
||||
|
||||
```bash
|
||||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
docker.litellm.ai/berriai/litellm:main-v1.83.7.rc.1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="pip" label="Pip">
|
||||
|
||||
```bash
|
||||
pip install litellm==1.83.7
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
:::warning
|
||||
|
||||
**Breaking change — Prometheus latency histogram buckets reduced.** The default `LATENCY_BUCKETS` set has been reduced from 35 to 18 boundaries to lower Prometheus cardinality. Dashboards and PromQL queries that reference specific `le=` bucket values may stop matching. Review your alerts/dashboards before upgrading and use `LATENCY_BUCKETS` env override to restore the previous boundaries if needed — [PR #25527](https://github.com/BerriAI/litellm/pull/25527).
|
||||
|
||||
:::
|
||||
|
||||
## Key Highlights
|
||||
|
||||
- **Per-User MCP OAuth Tokens** — [Each end-user can now hold their own OAuth tokens for interactive MCP server flows, isolating credentials across users](../../docs/mcp)
|
||||
- **Team Spend Logs RBAC** — Teams with the `/spend/logs` permission can view team-wide spend logs from the UI and API
|
||||
- **Bulk Team Permissions API** — New `POST /team/permissions_bulk_update` endpoint for updating member permissions across many teams in one call
|
||||
- **Azure Container Routing** — Container routing, managed container IDs, and delete-response parsing for Azure Responses API containers
|
||||
- **UI E2E Test Suite** — Playwright-based end-to-end tests for proxy admin, team, and key management flows now run in CI
|
||||
|
||||
---
|
||||
|
||||
## New Models / Updated Models
|
||||
|
||||
#### New Model Support (14 new models)
|
||||
|
||||
| Provider | Model | Context Window | Input ($/1M tokens) | Output ($/1M tokens) | Features |
|
||||
| -------- | ----- | -------------- | ------------------- | -------------------- | -------- |
|
||||
| AWS Bedrock (GovCloud) | `bedrock/us-gov-east-1/anthropic.claude-sonnet-4-5-20250929-v1:0` | 200K | $3.30 | $16.50 | Chat, vision, tool use, prompt caching, reasoning |
|
||||
| AWS Bedrock (GovCloud) | `bedrock/us-gov-west-1/anthropic.claude-sonnet-4-5-20250929-v1:0` | 200K | $3.30 | $16.50 | Chat, vision, tool use, prompt caching, reasoning |
|
||||
| AWS Bedrock (GovCloud) | `us-gov.anthropic.claude-sonnet-4-5-20250929-v1:0` | 200K | $3.30 | $16.50 | Bedrock Converse, with above-200K tier pricing |
|
||||
| Baseten | `baseten/MiniMaxAI/MiniMax-M2.5` | - | $0.30 | $1.20 | Chat |
|
||||
| Baseten | `baseten/nvidia/Nemotron-120B-A12B` | - | $0.30 | $0.75 | Chat |
|
||||
| Baseten | `baseten/zai-org/GLM-5` | - | $0.95 | $3.15 | Chat |
|
||||
| Baseten | `baseten/zai-org/GLM-4.7` | - | $0.60 | $2.20 | Chat |
|
||||
| Baseten | `baseten/zai-org/GLM-4.6` | - | $0.60 | $2.20 | Chat |
|
||||
| Baseten | `baseten/moonshotai/Kimi-K2.5` | - | $0.60 | $3.00 | Chat |
|
||||
| Baseten | `baseten/moonshotai/Kimi-K2-Thinking` | - | $0.60 | $2.50 | Chat |
|
||||
| Baseten | `baseten/moonshotai/Kimi-K2-Instruct-0905` | - | $0.60 | $2.50 | Chat |
|
||||
| Baseten | `baseten/openai/gpt-oss-120b` | - | $0.10 | $0.50 | Chat |
|
||||
| Baseten | `baseten/deepseek-ai/DeepSeek-V3.1` | - | $0.50 | $1.50 | Chat |
|
||||
| Baseten | `baseten/deepseek-ai/DeepSeek-V3-0324` | - | $0.77 | $0.77 | Chat |
|
||||
|
||||
#### Features
|
||||
|
||||
- **[AWS Bedrock](../../docs/providers/bedrock)**
|
||||
- AWS GovCloud mode support (`us-gov` prefix routing) - [PR #25254](https://github.com/BerriAI/litellm/pull/25254)
|
||||
- Update GovCloud Claude Sonnet 4.5 pricing, raise `max_tokens` to 8192, and add prompt-caching costs
|
||||
- Skip dummy `user` continue message when assistant prefix prefill is set - [PR #25419](https://github.com/BerriAI/litellm/pull/25419)
|
||||
- Avoid double-counting cache tokens in Anthropic Messages streaming usage - [PR #25517](https://github.com/BerriAI/litellm/pull/25517)
|
||||
- **[Anthropic](../../docs/providers/anthropic)**
|
||||
- Support `advisor_20260301` tool type - [PR #25525](https://github.com/BerriAI/litellm/pull/25525)
|
||||
- **[Triton](../../docs/providers/triton-inference-server)**
|
||||
- Embedding usage estimation for self-hosted Triton responses - [PR #25345](https://github.com/BerriAI/litellm/pull/25345)
|
||||
- **[Baseten](../../docs/providers/baseten)**
|
||||
- Add pricing entries for 11 new Baseten-hosted models - [PR #25358](https://github.com/BerriAI/litellm/pull/25358)
|
||||
- **[Google Gemini / Vertex AI](../../docs/providers/gemini)**
|
||||
- Mark applicable Gemini 2.5/3 models with `supports_service_tier`
|
||||
|
||||
### Bug Fixes
|
||||
|
||||
- **[AWS Bedrock](../../docs/providers/bedrock)**
|
||||
- Pass-through fix for Bedrock JSON body and multipart uploads - [PR #25464](https://github.com/BerriAI/litellm/pull/25464)
|
||||
- **[OpenAI](../../docs/providers/openai)**
|
||||
- Mock headers in `test_completion_fine_tuned_model` to stabilize tests - [PR #25444](https://github.com/BerriAI/litellm/pull/25444)
|
||||
|
||||
## LLM API Endpoints
|
||||
|
||||
#### Features
|
||||
|
||||
- **[Responses API](../../docs/response_api)**
|
||||
- Containers: Azure routing, managed container IDs, and delete-response parsing - [PR #25287](https://github.com/BerriAI/litellm/pull/25287)
|
||||
- WebSocket: append `?model=` to backend WebSocket URL so model selection routes correctly - [PR #25437](https://github.com/BerriAI/litellm/pull/25437)
|
||||
- **[OpenAI / Files API](../../docs/providers/openai)**
|
||||
- Add file content streaming support for OpenAI and related utilities - [PR #25450](https://github.com/BerriAI/litellm/pull/25450)
|
||||
- **[A2A](../../docs/mcp)**
|
||||
- Default 60-second timeout when creating an A2A client - [PR #25514](https://github.com/BerriAI/litellm/pull/25514)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- **[Responses API](../../docs/response_api)**
|
||||
- Map refusal `stop_reason` to `incomplete` status in streaming - [PR #25498](https://github.com/BerriAI/litellm/pull/25498)
|
||||
- Fix duplicate keyword argument error in Responses WebSocket path - [PR #25513](https://github.com/BerriAI/litellm/pull/25513)
|
||||
- **Router**
|
||||
- Pass `custom_llm_provider` to `get_llm_provider` for unprefixed model names - [PR #25334](https://github.com/BerriAI/litellm/pull/25334)
|
||||
- Fix tag-based routing when `encrypted_content_affinity` is enabled - [PR #25347](https://github.com/BerriAI/litellm/pull/25347)
|
||||
- **General**
|
||||
- Ensure spend/cost logging runs when `stream=True` for web-search interception - [PR #25424](https://github.com/BerriAI/litellm/pull/25424)
|
||||
|
||||
## Management Endpoints / UI
|
||||
|
||||
#### Features
|
||||
|
||||
- **Teams + Organizations**
|
||||
- New `POST /team/permissions_bulk_update` endpoint for bulk permission updates across teams - [PR #25239](https://github.com/BerriAI/litellm/pull/25239)
|
||||
- Team member permission `/spend/logs` to view team-wide spend logs (UI + RBAC) - [PR #25458](https://github.com/BerriAI/litellm/pull/25458)
|
||||
- Align org and team endpoint permission checks - [PR #25554](https://github.com/BerriAI/litellm/pull/25554)
|
||||
- **Virtual Keys**
|
||||
- Align `/v2/key/info` response handling with v1 - [PR #25313](https://github.com/BerriAI/litellm/pull/25313)
|
||||
- **Authentication / Routing**
|
||||
- Allow JWT to override OAuth2 routing without requiring global OAuth2 enablement - [PR #25252](https://github.com/BerriAI/litellm/pull/25252)
|
||||
- Consolidate route auth for UI and API tokens - [PR #25473](https://github.com/BerriAI/litellm/pull/25473)
|
||||
- Use parameterized query for `combined_view` token lookup - [PR #25467](https://github.com/BerriAI/litellm/pull/25467)
|
||||
- **Provider Credentials**
|
||||
- Per-team / per-project credential overrides via `model_config` metadata - [PR #24438](https://github.com/BerriAI/litellm/pull/24438)
|
||||
- **UI**
|
||||
- Improve browser storage handling and Dockerfile consistency - [PR #25384](https://github.com/BerriAI/litellm/pull/25384)
|
||||
- Align v1 guardrail and agent list responses with v2 field handling - [PR #25478](https://github.com/BerriAI/litellm/pull/25478)
|
||||
- Flush Tremor Tooltip timers in `user_edit_view` tests - [PR #25480](https://github.com/BerriAI/litellm/pull/25480)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- Improve input validation on management endpoints - [PR #25445](https://github.com/BerriAI/litellm/pull/25445)
|
||||
- Harden file path resolution in skill archive extraction - [PR #25475](https://github.com/BerriAI/litellm/pull/25475)
|
||||
|
||||
## AI Integrations
|
||||
|
||||
### Logging
|
||||
|
||||
- **[Ramp](../../docs/proxy/logging)**
|
||||
- Add Ramp as a built-in success callback - [PR #23769](https://github.com/BerriAI/litellm/pull/23769)
|
||||
- **[Langfuse](../../docs/proxy/logging#langfuse)**
|
||||
- Preserve proxy key-auth metadata on `/v1/messages` Langfuse traces - [PR #25448](https://github.com/BerriAI/litellm/pull/25448)
|
||||
- **[Prometheus](../../docs/proxy/logging#prometheus)**
|
||||
- Reduce default `LATENCY_BUCKETS` from 35 → 18 boundaries (see breaking-change note above) - [PR #25527](https://github.com/BerriAI/litellm/pull/25527)
|
||||
- **General**
|
||||
- S3 logging: retry with exponential backoff for transient 503/500 errors - [PR #25530](https://github.com/BerriAI/litellm/pull/25530)
|
||||
|
||||
### Guardrails
|
||||
|
||||
- Optional skip system message in unified guardrail inputs - [PR #25481](https://github.com/BerriAI/litellm/pull/25481)
|
||||
- Inline IAM: apply guardrail support - [PR #25241](https://github.com/BerriAI/litellm/pull/25241)
|
||||
- Preserve `dict` `HTTPException.detail` and Bedrock context in guardrail errors - [PR #25558](https://github.com/BerriAI/litellm/pull/25558)
|
||||
|
||||
## Spend Tracking, Budgets and Rate Limiting
|
||||
|
||||
- Session-TZ-independent date filtering for spend / error log queries - [PR #25542](https://github.com/BerriAI/litellm/pull/25542)
|
||||
- Batch-limit stale managed-object cleanup to prevent 300K+ row updates - [PR #25258](https://github.com/BerriAI/litellm/pull/25258)
|
||||
|
||||
## MCP Gateway
|
||||
|
||||
- **Per-user OAuth token storage for interactive MCP flows** - [PR #25441](https://github.com/BerriAI/litellm/pull/25441)
|
||||
- Block arbitrary command execution via MCP `stdio` transport - [PR #25343](https://github.com/BerriAI/litellm/pull/25343)
|
||||
- Document missing MCP per-user token environment variables in `config_settings` - [PR #25471](https://github.com/BerriAI/litellm/pull/25471)
|
||||
|
||||
## Performance / Loadbalancing / Reliability improvements
|
||||
|
||||
- Reduce Prometheus latency histogram cardinality (default buckets 35 → 18) - [PR #25527](https://github.com/BerriAI/litellm/pull/25527)
|
||||
- S3 retry with exponential backoff for transient errors - [PR #25530](https://github.com/BerriAI/litellm/pull/25530)
|
||||
|
||||
## Documentation Updates
|
||||
|
||||
- Add Docker Image Security Guide covering cosign verification and deployment best practices - [PR #25439](https://github.com/BerriAI/litellm/pull/25439)
|
||||
- Document April townhall announcements - [PR #25537](https://github.com/BerriAI/litellm/pull/25537)
|
||||
- Document missing MCP per-user token env vars - [PR #25471](https://github.com/BerriAI/litellm/pull/25471)
|
||||
- Add "Screenshots / Proof of Fix" section to PR template - [PR #25564](https://github.com/BerriAI/litellm/pull/25564)
|
||||
|
||||
## Infrastructure / Security Notes
|
||||
|
||||
- Pin cosign.pub verification to initial commit hash - [PR #25273](https://github.com/BerriAI/litellm/pull/25273)
|
||||
- Fix node-gyp symlink path after npm upgrade in Dockerfile - [PR #25048](https://github.com/BerriAI/litellm/pull/25048)
|
||||
- `Dockerfile.non_root`: handle missing `.npmrc` gracefully - [PR #25307](https://github.com/BerriAI/litellm/pull/25307)
|
||||
- Add Playwright E2E tests with local PostgreSQL - [PR #25126](https://github.com/BerriAI/litellm/pull/25126)
|
||||
- UI E2E tests for proxy admin team and key management - [PR #25365](https://github.com/BerriAI/litellm/pull/25365)
|
||||
- Migrate Redis caching tests from GHA to CircleCI - [PR #25354](https://github.com/BerriAI/litellm/pull/25354)
|
||||
- Update `check_responses_cost` tests for `_expire_stale_rows` - [PR #25299](https://github.com/BerriAI/litellm/pull/25299)
|
||||
- Raise global vitest timeout and remove per-test overrides - [PR #25468](https://github.com/BerriAI/litellm/pull/25468)
|
||||
- Version bumps and UI rebuilds: [PR #25316](https://github.com/BerriAI/litellm/pull/25316), [PR #25528](https://github.com/BerriAI/litellm/pull/25528), [PR #25578](https://github.com/BerriAI/litellm/pull/25578), [PR #25571](https://github.com/BerriAI/litellm/pull/25571), [PR #25573](https://github.com/BerriAI/litellm/pull/25573), [PR #25577](https://github.com/BerriAI/litellm/pull/25577)
|
||||
|
||||
## New Contributors
|
||||
|
||||
* @kedarthakkar made their first contribution in https://github.com/BerriAI/litellm/pull/23769
|
||||
* @csoni-cweave made their first contribution in https://github.com/BerriAI/litellm/pull/25441
|
||||
* @jimmychen-p72 made their first contribution in https://github.com/BerriAI/litellm/pull/25530
|
||||
|
||||
**Full Changelog**: https://github.com/BerriAI/litellm/compare/v1.83.3.rc.1...v1.83.7.rc.1
|
||||
|
|
@ -254,6 +254,11 @@ const sidebars = {
|
|||
id: "image_generation",
|
||||
label: "image_generation()",
|
||||
},
|
||||
{
|
||||
type: "doc",
|
||||
id: "completion/prompt_compression",
|
||||
label: "compress()",
|
||||
},
|
||||
{
|
||||
type: "doc",
|
||||
id: "audio_transcription",
|
||||
|
|
@ -1144,6 +1149,7 @@ const sidebars = {
|
|||
label: "Troubleshooting",
|
||||
items: [
|
||||
"troubleshoot/ui_issues",
|
||||
"troubleshoot/cost_discrepancy",
|
||||
"mcp_troubleshoot",
|
||||
{
|
||||
type: "category",
|
||||
|
|
@ -1280,6 +1286,7 @@ const learnSidebar = {
|
|||
items: [
|
||||
"completion/prefix",
|
||||
"completion/predict_outputs",
|
||||
"completion/prompt_compression",
|
||||
"completion/message_trimming",
|
||||
"completion/prompt_caching",
|
||||
"completion/prompt_formatting",
|
||||
|
|
|
|||
|
|
@ -1,6 +1,10 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
:::note Security Update
|
||||
The Trivy supply-chain compromise has been contained :tada: . All affected packages have been deleted and current releases are free of the compromised code/component. Please refer to our [Security Townhall](/blog/security-townhall-updates) for a deeper understanding of the problem, and [CI/CD v2](/blog/ci-cd-v2-improvements) for how we're improving moving forward.
|
||||
:::
|
||||
|
||||
# LiteLLM - Getting Started
|
||||
|
||||
https://github.com/BerriAI/litellm
|
||||
|
|
|
|||

Binary file not shown.
|
After Width: | Height: | Size: 509 KiB |

Binary file not shown.
|
After Width: | Height: | Size: 445 KiB |

Binary file not shown.
|
After Width: | Height: | Size: 296 KiB |

Binary file not shown.
|
After Width: | Height: | Size: 281 KiB |
|
|
@ -0,0 +1,2 @@
|
|||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_MCPServerTable" ADD COLUMN IF NOT EXISTS "instructions" TEXT;
|
||||
|
|
@ -0,0 +1,12 @@
|
|||
-- CreateIndex (CONCURRENTLY)
|
||||
--
|
||||
-- Disclaimer:
|
||||
-- - CREATE INDEX CONCURRENTLY cannot run inside a transaction. This migration must stay a
|
||||
-- single statement so Prisma Migrate on PostgreSQL can apply it outside a transaction.
|
||||
-- - Builds are slower and use more I/O than a blocking CREATE INDEX; if the build is
|
||||
-- interrupted, Postgres may leave an INVALID index that must be dropped and recreated.
|
||||
-- - Do not edit this file after it has been applied to any database: Prisma checksums
|
||||
-- migrations; add a new migration instead.
|
||||
-- - Requires PostgreSQL that supports CONCURRENTLY with IF NOT EXISTS (use a new migration
|
||||
-- without IF NOT EXISTS if you must support older versions).
|
||||
CREATE INDEX CONCURRENTLY IF NOT EXISTS "LiteLLM_HealthCheckTable_model_id_model_name_checked_at_idx" ON "LiteLLM_HealthCheckTable"("model_id", "model_name", "checked_at" DESC);
|
||||
|
|
@ -289,6 +289,7 @@ model LiteLLM_MCPServerTable {
|
|||
server_name String?
|
||||
alias String?
|
||||
description String?
|
||||
instructions String?
|
||||
url String?
|
||||
spec_path String?
|
||||
transport String @default("sse")
|
||||
|
|
@ -1045,6 +1046,7 @@ model LiteLLM_HealthCheckTable {
|
|||
@@index([model_name])
|
||||
@@index([checked_at])
|
||||
@@index([status])
|
||||
@@index([model_id, model_name, checked_at(sort: Desc)], map: "LiteLLM_HealthCheckTable_model_id_model_name_checked_at_idx")
|
||||
}
|
||||
|
||||
// Search Tools table for storing search tool configurations
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
[project]
|
||||
name = "litellm-proxy-extras"
|
||||
version = "0.4.65"
|
||||
version = "0.4.66"
|
||||
description = "Additional files for the LiteLLM Proxy. Reduces the size of the main litellm package."
|
||||
readme = "README.md"
|
||||
requires-python = ">=3.9"
|
||||
|
|
@ -25,7 +25,7 @@ required-version = "==0.10.9"
|
|||
module-root = ""
|
||||
|
||||
[tool.commitizen]
|
||||
version = "0.4.65"
|
||||
version = "0.4.66"
|
||||
version_files = [
|
||||
"pyproject.toml:^version",
|
||||
"../pyproject.toml:litellm-proxy-extras==",
|
||||
|
|
|
|||
|
|
@ -1176,6 +1176,7 @@ from litellm.types.utils import LlmProviders
|
|||
|
||||
## Lazy loading this is not straightforward, will leave it here for now.
|
||||
from .main import * # type: ignore
|
||||
from .compression import compress # type: ignore[no-redef]
|
||||
|
||||
# Skills API
|
||||
from .skills.main import (
|
||||
|
|
|
|||
13
litellm/_internal_context.py
Normal file
13
litellm/_internal_context.py
Normal file
|
|
@ -0,0 +1,13 @@
|
|||
"""
|
||||
Internal request context for LiteLLM.
|
||||
|
||||
Provides a ContextVar-based mechanism for internal signals that must not
|
||||
be settable from user input. Context variables are scoped to the current
|
||||
asyncio task and cannot be injected via HTTP request bodies.
|
||||
"""
|
||||
|
||||
from contextvars import ContextVar
|
||||
|
||||
# When True, suppresses async logging and billing for internal sub-calls
|
||||
# (e.g., emulated file-search steps that make nested LLM calls).
|
||||
is_internal_call: ContextVar[bool] = ContextVar("is_internal_call", default=False)
|
||||
|
|
@ -86,6 +86,8 @@ _SECRET_RE = _build_secret_patterns()
|
|||
|
||||
|
||||
def _redact_string(value: str) -> str:
|
||||
if not _ENABLE_SECRET_REDACTION:
|
||||
return value
|
||||
return _SECRET_RE.sub(_REDACTED, value)
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -71,12 +71,12 @@
|
|||
"computer-use-2025-01-24": "computer-use-2025-01-24",
|
||||
"computer-use-2025-11-24": "computer-use-2025-11-24",
|
||||
"context-1m-2025-08-07": "context-1m-2025-08-07",
|
||||
"context-management-2025-06-27": "context-management-2025-06-27",
|
||||
"context-management-2025-06-27": null,
|
||||
"effort-2025-11-24": null,
|
||||
"fast-mode-2026-02-01": null,
|
||||
"files-api-2025-04-14": null,
|
||||
"fine-grained-tool-streaming-2025-05-14": null,
|
||||
"interleaved-thinking-2025-05-14": "interleaved-thinking-2025-05-14",
|
||||
"interleaved-thinking-2025-05-14": null,
|
||||
"mcp-client-2025-11-20": null,
|
||||
"mcp-client-2025-04-04": null,
|
||||
"mcp-servers-2025-12-04": null,
|
||||
|
|
@ -102,12 +102,12 @@
|
|||
"computer-use-2025-01-24": "computer-use-2025-01-24",
|
||||
"computer-use-2025-11-24": "computer-use-2025-11-24",
|
||||
"context-1m-2025-08-07": "context-1m-2025-08-07",
|
||||
"context-management-2025-06-27": "context-management-2025-06-27",
|
||||
"context-management-2025-06-27": null,
|
||||
"effort-2025-11-24": null,
|
||||
"fast-mode-2026-02-01": null,
|
||||
"files-api-2025-04-14": null,
|
||||
"fine-grained-tool-streaming-2025-05-14": null,
|
||||
"interleaved-thinking-2025-05-14": "interleaved-thinking-2025-05-14",
|
||||
"interleaved-thinking-2025-05-14": null,
|
||||
"mcp-client-2025-11-20": null,
|
||||
"mcp-client-2025-04-04": null,
|
||||
"mcp-servers-2025-12-04": null,
|
||||
|
|
|
|||
|
|
@ -312,8 +312,11 @@ class Cache:
|
|||
verbose_logger.debug("\nCreated cache key: %s", cache_key)
|
||||
hashed_cache_key = Cache._get_hashed_cache_key(cache_key)
|
||||
hashed_cache_key = self._add_namespace_to_cache_key(hashed_cache_key, **kwargs)
|
||||
# Remove preset_cache_key from kwargs to avoid "got multiple values" TypeError
|
||||
# when kwargs already contains preset_cache_key from upstream callers
|
||||
kwargs_for_preset = {k: v for k, v in kwargs.items() if k != "preset_cache_key"}
|
||||
self._set_preset_cache_key_in_kwargs(
|
||||
preset_cache_key=hashed_cache_key, **kwargs
|
||||
preset_cache_key=hashed_cache_key, **kwargs_for_preset
|
||||
)
|
||||
return hashed_cache_key
|
||||
|
||||
|
|
|
|||
|
|
@ -161,9 +161,10 @@ class InMemoryCache(BaseCache):
|
|||
if self.max_size_in_memory == 0:
|
||||
return # Don't cache anything if max size is 0
|
||||
|
||||
if len(self.cache_dict) >= self.max_size_in_memory:
|
||||
# only evict when cache is full
|
||||
self.evict_cache()
|
||||
# Always prune expired/outdated heap roots before inserting.
|
||||
# This keeps expiration_heap bounded even when the live cache stays
|
||||
# below max_size_in_memory and keys are reinserted after TTL expiry.
|
||||
self.evict_cache()
|
||||
if not self.check_value_size(value):
|
||||
return
|
||||
|
||||
|
|
|
|||
3
litellm/compression/__init__.py
Normal file
3
litellm/compression/__init__.py
Normal file
|
|
@ -0,0 +1,3 @@
|
|||
from litellm.compression.compress import compress
|
||||
|
||||
__all__ = ["compress"]
|
||||
255
litellm/compression/compress.py
Normal file
255
litellm/compression/compress.py
Normal file
|
|
@ -0,0 +1,255 @@
|
|||
"""
|
||||
Main compress() function — orchestrates BM25/embedding scoring, message stubbing,
|
||||
and retrieval tool injection.
|
||||
"""
|
||||
|
||||
from typing import Any, Dict, List, Optional, Set, Union, cast
|
||||
|
||||
from litellm.caching.dual_cache import DualCache
|
||||
from litellm.compression.message_stubbing import (
|
||||
extract_key,
|
||||
stub_message,
|
||||
truncate_message,
|
||||
)
|
||||
from litellm.compression.retrieval_tool import build_retrieval_tool
|
||||
from litellm.compression.scoring.bm25 import bm25_score_messages
|
||||
from litellm.litellm_core_utils.token_counter import token_counter
|
||||
from litellm.types.compression import CompressedResult
|
||||
from litellm.types.utils import AllMessageValues, Message
|
||||
|
||||
|
||||
def _extract_last_user_message(messages: List[dict]) -> str:
|
||||
"""Return the text content of the last user message."""
|
||||
for msg in reversed(messages):
|
||||
if msg.get("role") == "user":
|
||||
content = msg.get("content", "")
|
||||
if isinstance(content, str):
|
||||
return content
|
||||
if isinstance(content, list):
|
||||
parts = []
|
||||
for part in content:
|
||||
if isinstance(part, dict) and part.get("type") == "text":
|
||||
parts.append(part.get("text", ""))
|
||||
elif isinstance(part, str):
|
||||
parts.append(part)
|
||||
return " ".join(parts)
|
||||
return ""
|
||||
|
||||
|
||||
def _get_protected_indices(messages: List[dict]) -> List[int]:
|
||||
"""
|
||||
Return indices of messages that must never be compressed:
|
||||
- All system messages
|
||||
- The last user message
|
||||
- The last assistant message
|
||||
"""
|
||||
protected: List[int] = []
|
||||
|
||||
last_user_idx = None
|
||||
last_assistant_idx = None
|
||||
|
||||
for i, msg in enumerate(messages):
|
||||
role = msg.get("role", "")
|
||||
if role == "system":
|
||||
protected.append(i)
|
||||
elif role == "user":
|
||||
last_user_idx = i
|
||||
elif role == "assistant":
|
||||
last_assistant_idx = i
|
||||
|
||||
if last_user_idx is not None:
|
||||
protected.append(last_user_idx)
|
||||
if last_assistant_idx is not None:
|
||||
protected.append(last_assistant_idx)
|
||||
|
||||
return protected
|
||||
|
||||
|
||||
def _combine_scores(
|
||||
bm25_scores: List[float],
|
||||
emb_scores: List[float],
|
||||
bm25_weight: float = 0.4,
|
||||
) -> List[float]:
|
||||
"""Weighted average of BM25 and embedding scores, with min-max normalization."""
|
||||
|
||||
def _normalize(scores: List[float]) -> List[float]:
|
||||
min_s = min(scores) if scores else 0.0
|
||||
max_s = max(scores) if scores else 0.0
|
||||
rng = max_s - min_s
|
||||
if rng == 0:
|
||||
return [0.0] * len(scores)
|
||||
return [(s - min_s) / rng for s in scores]
|
||||
|
||||
norm_bm25 = _normalize(bm25_scores)
|
||||
norm_emb = _normalize(emb_scores)
|
||||
emb_weight = 1.0 - bm25_weight
|
||||
|
||||
return [bm25_weight * b + emb_weight * e for b, e in zip(norm_bm25, norm_emb)]
|
||||
|
||||
|
||||
def compress(
|
||||
messages: List[dict],
|
||||
model: str,
|
||||
compression_trigger: int = 200_000,
|
||||
compression_target: Optional[int] = None,
|
||||
embedding_model: Optional[str] = None,
|
||||
embedding_model_params: Optional[Dict[str, Any]] = None,
|
||||
compression_cache: Optional[DualCache] = None,
|
||||
) -> CompressedResult:
|
||||
"""
|
||||
Compress a list of messages by replacing low-relevance content with stubs.
|
||||
|
||||
Messages below ``compression_trigger`` tokens pass through unchanged.
|
||||
Messages above are scored with BM25 (and optionally embeddings), ranked,
|
||||
and the lowest-relevance messages are replaced with stubs. Originals are
|
||||
cached and a retrieval tool is injected so the model can recover dropped
|
||||
content on demand.
|
||||
|
||||
Parameters:
|
||||
messages: The conversation messages to (potentially) compress.
|
||||
model: The LLM model name — used for token counting.
|
||||
compression_trigger: Only compress if input exceeds this token count.
|
||||
compression_target: Target token count after compression.
|
||||
Defaults to ``compression_trigger // 2``.
|
||||
embedding_model: If provided, use BM25 + embeddings for scoring.
|
||||
If ``None``, BM25 only.
|
||||
embedding_model_params: Optional kwargs forwarded to
|
||||
``litellm.embedding()`` when ``embedding_model`` is set.
|
||||
compression_cache: Passed through to ``litellm.embedding()`` for
|
||||
cross-turn caching of embedding vectors.
|
||||
|
||||
Returns:
|
||||
A ``CompressedResult`` dict containing compressed messages, token
|
||||
counts, a cache of original content, and the retrieval tool definition.
|
||||
"""
|
||||
if compression_target is None:
|
||||
compression_target = compression_trigger * 7 // 10
|
||||
|
||||
original_tokens = token_counter(
|
||||
model=model, messages=cast(List[Union[AllMessageValues, Message]], messages)
|
||||
)
|
||||
|
||||
# Pass through if below trigger
|
||||
if original_tokens <= compression_trigger:
|
||||
return CompressedResult(
|
||||
messages=messages,
|
||||
original_tokens=original_tokens,
|
||||
compressed_tokens=original_tokens,
|
||||
compression_ratio=0.0,
|
||||
cache={},
|
||||
tools=[],
|
||||
)
|
||||
|
||||
# Extract query for relevance scoring
|
||||
query = _extract_last_user_message(messages)
|
||||
|
||||
# Score each message
|
||||
bm25_scores = bm25_score_messages(query, messages)
|
||||
|
||||
if embedding_model:
|
||||
from litellm.compression.scoring.embedding_scorer import (
|
||||
embedding_score_messages,
|
||||
)
|
||||
|
||||
emb_scores = embedding_score_messages(
|
||||
query,
|
||||
messages,
|
||||
model=embedding_model,
|
||||
cache=compression_cache,
|
||||
embedding_model_params=embedding_model_params,
|
||||
)
|
||||
combined_scores = _combine_scores(bm25_scores, emb_scores, bm25_weight=0.4)
|
||||
else:
|
||||
combined_scores = bm25_scores
|
||||
|
||||
# Sort message indices by score descending
|
||||
ranked_indices = sorted(
|
||||
range(len(messages)),
|
||||
key=lambda i: combined_scores[i],
|
||||
reverse=True,
|
||||
)
|
||||
|
||||
# Protected messages are never compressed
|
||||
protected_indices = _get_protected_indices(messages)
|
||||
kept_indices: Set[int] = set(protected_indices)
|
||||
|
||||
# Count tokens for protected messages
|
||||
current_tokens = 0
|
||||
for i in kept_indices:
|
||||
current_tokens += token_counter(
|
||||
model=model, text=messages[i].get("content", "") or ""
|
||||
)
|
||||
|
||||
# Fill token budget from highest-scoring messages.
|
||||
# For each candidate (ranked by relevance):
|
||||
# - If it fits entirely → keep it as-is.
|
||||
# - If it doesn't fit but there's meaningful remaining budget → truncate it
|
||||
# to fill as much of the budget as possible.
|
||||
# - Otherwise → stub it (pointer only, content goes to cache).
|
||||
# Multiple messages may be truncated so we preserve partial content from
|
||||
# several high-scoring messages rather than fully stubbing all but one.
|
||||
truncated_overrides: Dict[int, dict] = {} # idx -> truncated message dict
|
||||
|
||||
for idx in ranked_indices:
|
||||
if idx in kept_indices:
|
||||
continue
|
||||
msg_content = messages[idx].get("content", "") or ""
|
||||
msg_tokens = token_counter(model=model, text=msg_content)
|
||||
remaining = compression_target - current_tokens
|
||||
|
||||
if remaining <= 0:
|
||||
break # budget exhausted
|
||||
|
||||
if current_tokens + msg_tokens <= compression_target:
|
||||
# Fits entirely
|
||||
kept_indices.add(idx)
|
||||
current_tokens += msg_tokens
|
||||
elif remaining >= 100:
|
||||
# Too large to fit whole, but we have budget — truncate it.
|
||||
truncated = truncate_message(messages[idx], remaining)
|
||||
truncated_tokens = token_counter(
|
||||
model=model,
|
||||
text=truncated.get("content", "") or "",
|
||||
)
|
||||
truncated_overrides[idx] = truncated
|
||||
kept_indices.add(idx)
|
||||
current_tokens += truncated_tokens
|
||||
|
||||
# Build compressed messages and cache
|
||||
compressed_messages: List[dict] = []
|
||||
cache: Dict[str, str] = {}
|
||||
used_keys: Set[str] = set()
|
||||
|
||||
for i, msg in enumerate(messages):
|
||||
if i in kept_indices:
|
||||
# Use the truncated version if we made one, otherwise the original
|
||||
compressed_messages.append(truncated_overrides.get(i, msg))
|
||||
else:
|
||||
key = extract_key(msg, fallback_index=i, used_keys=used_keys)
|
||||
content = msg.get("content", "")
|
||||
if isinstance(content, list):
|
||||
content = " ".join(
|
||||
p.get("text", "") if isinstance(p, dict) else str(p)
|
||||
for p in content
|
||||
)
|
||||
cache[key] = content
|
||||
compressed_messages.append(stub_message(msg, key))
|
||||
|
||||
# Build retrieval tool
|
||||
tools = [build_retrieval_tool(list(cache.keys()))] if cache else []
|
||||
|
||||
compressed_tokens = token_counter(
|
||||
model=model,
|
||||
messages=cast(List[Union[AllMessageValues, Message]], compressed_messages),
|
||||
)
|
||||
|
||||
return CompressedResult(
|
||||
messages=compressed_messages,
|
||||
original_tokens=original_tokens,
|
||||
compressed_tokens=compressed_tokens,
|
||||
compression_ratio=round(1 - (compressed_tokens / original_tokens), 4)
|
||||
if original_tokens > 0
|
||||
else 0.0,
|
||||
cache=cache,
|
||||
tools=tools,
|
||||
)
|
||||
45
litellm/compression/content_detection.py
Normal file
45
litellm/compression/content_detection.py
Normal file
|
|
@ -0,0 +1,45 @@
|
|||
"""
|
||||
Auto-detect content type per message: code, JSON, or text.
|
||||
"""
|
||||
|
||||
import json
|
||||
import re
|
||||
|
||||
|
||||
_CODE_KEYWORDS = re.compile(
|
||||
r"\b(?:def |function |class |import |from |require\(|#include|fn |func |const |let |var |public |private |static )\b"
|
||||
)
|
||||
|
||||
|
||||
def detect_content_type(content: str) -> str:
|
||||
"""
|
||||
Detect whether content is code, JSON, or plain text.
|
||||
|
||||
Returns one of: "code", "json", "text"
|
||||
"""
|
||||
stripped = content.strip()
|
||||
if not stripped:
|
||||
return "text"
|
||||
|
||||
# Check JSON
|
||||
if stripped[0] in ("{", "["):
|
||||
try:
|
||||
json.loads(stripped)
|
||||
return "json"
|
||||
except (json.JSONDecodeError, ValueError):
|
||||
pass
|
||||
|
||||
# Check code indicators
|
||||
# Sample first 5000 chars for performance
|
||||
sample = stripped[:5000]
|
||||
keyword_matches = len(_CODE_KEYWORDS.findall(sample))
|
||||
lines = sample.split("\n")
|
||||
indented_lines = sum(
|
||||
1 for line in lines if line.startswith((" ", "\t")) and line.strip()
|
||||
)
|
||||
|
||||
# If we see multiple code keywords or significant indentation, it's likely code
|
||||
if keyword_matches >= 3 or (indented_lines > len(lines) * 0.3 and len(lines) > 5):
|
||||
return "code"
|
||||
|
||||
return "text"
|
||||
120
litellm/compression/message_stubbing.py
Normal file
120
litellm/compression/message_stubbing.py
Normal file
|
|
@ -0,0 +1,120 @@
|
|||
"""
|
||||
Replace messages with compact stubs and extract human-readable keys.
|
||||
"""
|
||||
|
||||
import re
|
||||
from typing import Set
|
||||
|
||||
from litellm.compression.content_detection import detect_content_type
|
||||
|
||||
# Patterns for extracting file paths from content
|
||||
_FILE_PATH_PATTERNS = [
|
||||
re.compile(r"^#\s*(\S+\.\w+)", re.MULTILINE), # # filename.py
|
||||
re.compile(r"^//\s*(\S+\.\w+)", re.MULTILINE), # // filename.js
|
||||
re.compile(r"^File:\s*(\S+)", re.MULTILINE), # File: path/to/file
|
||||
re.compile(r"^---\s*(\S+\.\w+)", re.MULTILINE), # --- filename.ext
|
||||
re.compile(r"`(\S+\.\w{1,5})`"), # `filename.ext` in backticks
|
||||
]
|
||||
|
||||
|
||||
def extract_key(message: dict, fallback_index: int, used_keys: Set[str]) -> str:
|
||||
"""
|
||||
Extract a human-readable key for the message.
|
||||
|
||||
Looks for file path patterns in the content. Falls back to message_{index}.
|
||||
Handles duplicates by appending _2, _3, etc.
|
||||
"""
|
||||
content = message.get("content", "")
|
||||
if isinstance(content, list):
|
||||
content = " ".join(
|
||||
p.get("text", "") if isinstance(p, dict) else str(p) for p in content
|
||||
)
|
||||
|
||||
key = None
|
||||
for pattern in _FILE_PATH_PATTERNS:
|
||||
match = pattern.search(content[:2000]) # Only search the beginning
|
||||
if match:
|
||||
# Use just the filename, not full path
|
||||
path = match.group(1)
|
||||
key = path.split("/")[-1]
|
||||
break
|
||||
|
||||
if key is None:
|
||||
key = f"message_{fallback_index}"
|
||||
|
||||
# Handle duplicates
|
||||
base_key = key
|
||||
counter = 2
|
||||
while key in used_keys:
|
||||
key = f"{base_key}_{counter}"
|
||||
counter += 1
|
||||
|
||||
used_keys.add(key)
|
||||
return key
|
||||
|
||||
|
||||
def stub_message(message: dict, key: str) -> dict:
|
||||
"""
|
||||
Replace message content with a compact stub.
|
||||
|
||||
Returns a new message dict with the same role but content replaced
|
||||
with a short description referencing the retrieval tool.
|
||||
"""
|
||||
content = message.get("content", "")
|
||||
if isinstance(content, list):
|
||||
content = " ".join(
|
||||
p.get("text", "") if isinstance(p, dict) else str(p) for p in content
|
||||
)
|
||||
|
||||
line_count = content.count("\n") + 1
|
||||
content_type = detect_content_type(content)
|
||||
|
||||
stub_content = (
|
||||
f"[Compressed: {key} — {line_count} lines, {content_type}. "
|
||||
f"Use litellm_content_retrieve tool to get full content.]"
|
||||
)
|
||||
|
||||
return {**message, "content": stub_content}
|
||||
|
||||
|
||||
def truncate_message(message: dict, max_tokens: int) -> dict:
|
||||
"""
|
||||
Truncate a message's content to approximately max_tokens by keeping
|
||||
the first 70% and last 30% of lines with a separator in between.
|
||||
|
||||
Uses line-based splitting to preserve code structure (function
|
||||
boundaries, indentation) rather than word-based splitting which
|
||||
mangles code.
|
||||
|
||||
Used when a message is too large to fit entirely in the budget but
|
||||
too relevant to fully stub out.
|
||||
"""
|
||||
content = message.get("content", "")
|
||||
if isinstance(content, list):
|
||||
content = " ".join(
|
||||
p.get("text", "") if isinstance(p, dict) else str(p) for p in content
|
||||
)
|
||||
|
||||
# Rough conversion: 1 token ≈ 3 characters
|
||||
target_chars = max(100, max_tokens * 3)
|
||||
|
||||
if len(content) <= target_chars:
|
||||
return {**message, "content": content}
|
||||
|
||||
lines = content.split("\n")
|
||||
|
||||
# Estimate target line count from character budget
|
||||
avg_line_len = max(1, len(content) // max(1, len(lines)))
|
||||
target_lines = max(2, target_chars // avg_line_len)
|
||||
|
||||
if len(lines) <= target_lines:
|
||||
return {**message, "content": content}
|
||||
|
||||
first_count = (target_lines * 7) // 10
|
||||
last_count = target_lines - first_count
|
||||
truncated = (
|
||||
"\n".join(lines[:first_count])
|
||||
+ "\n...[truncated for context window]...\n"
|
||||
+ "\n".join(lines[-last_count:])
|
||||
)
|
||||
return {**message, "content": truncated}
|
||||
35
litellm/compression/retrieval_tool.py
Normal file
35
litellm/compression/retrieval_tool.py
Normal file
|
|
@ -0,0 +1,35 @@
|
|||
"""
|
||||
Build the litellm_content_retrieve tool definition for the LLM.
|
||||
"""
|
||||
|
||||
from typing import List
|
||||
|
||||
|
||||
def build_retrieval_tool(available_keys: List[str]) -> dict:
|
||||
"""
|
||||
Return an OpenAI-format tool definition that lets the model
|
||||
retrieve the full content of a compressed message.
|
||||
"""
|
||||
return {
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "litellm_content_retrieve",
|
||||
"description": (
|
||||
"Retrieve the full content of a file or message that was "
|
||||
"compressed to save tokens. Use this when you need the complete "
|
||||
"content to answer accurately. Available keys: "
|
||||
+ ", ".join(available_keys)
|
||||
),
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"key": {
|
||||
"type": "string",
|
||||
"description": "The identifier of the content to retrieve",
|
||||
"enum": available_keys,
|
||||
}
|
||||
},
|
||||
"required": ["key"],
|
||||
},
|
||||
},
|
||||
}
|
||||
4
litellm/compression/scoring/__init__.py
Normal file
4
litellm/compression/scoring/__init__.py
Normal file
|
|
@ -0,0 +1,4 @@
|
|||
from litellm.compression.scoring.bm25 import bm25_score_messages
|
||||
from litellm.compression.scoring.embedding_scorer import embedding_score_messages
|
||||
|
||||
__all__ = ["bm25_score_messages", "embedding_score_messages"]
|
||||
123
litellm/compression/scoring/bm25.py
Normal file
123
litellm/compression/scoring/bm25.py
Normal file
|
|
@ -0,0 +1,123 @@
|
|||
"""
|
||||
Pure Python BM25 (Okapi BM25) relevance scorer.
|
||||
|
||||
No external dependencies — uses only stdlib.
|
||||
"""
|
||||
|
||||
import math
|
||||
import re
|
||||
from collections import Counter
|
||||
from typing import Dict, List
|
||||
|
||||
|
||||
def _tokenize(text: str) -> List[str]:
|
||||
"""Split text into lowercase tokens on word boundaries."""
|
||||
return re.findall(r"[a-z0-9_]+", text.lower())
|
||||
|
||||
|
||||
def _extract_content(message: dict) -> str:
|
||||
"""Extract text content from a message dict."""
|
||||
content = message.get("content", "")
|
||||
if isinstance(content, str):
|
||||
return content
|
||||
if isinstance(content, list):
|
||||
parts = []
|
||||
for part in content:
|
||||
if isinstance(part, dict) and part.get("type") == "text":
|
||||
parts.append(part.get("text", ""))
|
||||
elif isinstance(part, str):
|
||||
parts.append(part)
|
||||
return " ".join(parts)
|
||||
return ""
|
||||
|
||||
|
||||
def bm25_score_messages(
|
||||
query: str,
|
||||
messages: List[dict],
|
||||
k1: float = 1.5,
|
||||
b: float = 0.75,
|
||||
) -> List[float]:
|
||||
"""
|
||||
Score each message's relevance to the query using BM25 (Okapi BM25).
|
||||
|
||||
Parameters:
|
||||
query: The reference text to score against (typically the last user message).
|
||||
messages: List of message dicts with "content" fields.
|
||||
k1: Term frequency saturation parameter.
|
||||
b: Length normalization parameter.
|
||||
|
||||
Returns:
|
||||
List of float scores, one per message. Higher = more relevant.
|
||||
"""
|
||||
query_terms = _tokenize(query)
|
||||
if not query_terms:
|
||||
return [0.0] * len(messages)
|
||||
|
||||
# Tokenize all documents
|
||||
doc_tokens: List[List[str]] = []
|
||||
for msg in messages:
|
||||
doc_tokens.append(_tokenize(_extract_content(msg)))
|
||||
|
||||
n = len(doc_tokens)
|
||||
if n == 0:
|
||||
return []
|
||||
|
||||
# Average document length
|
||||
doc_lengths = [len(dt) for dt in doc_tokens]
|
||||
avgdl = sum(doc_lengths) / n if n > 0 else 1.0
|
||||
|
||||
# Document frequency for each term
|
||||
df: Dict[str, int] = {}
|
||||
for dt in doc_tokens:
|
||||
seen = set(dt)
|
||||
for term in seen:
|
||||
df[term] = df.get(term, 0) + 1
|
||||
|
||||
# IDF for query terms
|
||||
idf: Dict[str, float] = {}
|
||||
for term in set(query_terms):
|
||||
term_df = df.get(term, 0)
|
||||
# Standard BM25 IDF: log((N - df + 0.5) / (df + 0.5) + 1)
|
||||
idf[term] = math.log((n - term_df + 0.5) / (term_df + 0.5) + 1.0)
|
||||
|
||||
# Build a prefix-expansion map per document: for each query term, find all
|
||||
# document tokens that start with that term (min 4 chars match). This lets
|
||||
# "cook" match "cooking" and "auth" match "authentication" without a full
|
||||
# stemmer dependency.
|
||||
def _expand_tf(query_term: str, tf_counts: Counter) -> int: # type: ignore[type-arg]
|
||||
"""Sum TF across all doc tokens that are prefixed by query_term."""
|
||||
exact = tf_counts.get(query_term, 0)
|
||||
if exact:
|
||||
return exact
|
||||
if len(query_term) < 4:
|
||||
return 0
|
||||
return sum(
|
||||
count
|
||||
for token, count in tf_counts.items()
|
||||
if token != query_term and token.startswith(query_term)
|
||||
)
|
||||
|
||||
# Score each document
|
||||
scores: List[float] = []
|
||||
for i, dt in enumerate(doc_tokens):
|
||||
if not dt:
|
||||
scores.append(0.0)
|
||||
continue
|
||||
|
||||
tf_counts = Counter(dt)
|
||||
dl = doc_lengths[i]
|
||||
score = 0.0
|
||||
|
||||
for term in query_terms:
|
||||
if term not in idf:
|
||||
continue
|
||||
tf = _expand_tf(term, tf_counts)
|
||||
if tf == 0:
|
||||
continue
|
||||
numerator = tf * (k1 + 1)
|
||||
denominator = tf + k1 * (1 - b + b * dl / avgdl)
|
||||
score += idf[term] * numerator / denominator
|
||||
|
||||
scores.append(score)
|
||||
|
||||
return scores
|
||||
95
litellm/compression/scoring/embedding_scorer.py
Normal file
95
litellm/compression/scoring/embedding_scorer.py
Normal file
|
|
@ -0,0 +1,95 @@
|
|||
"""
|
||||
Semantic scoring via litellm.embedding().
|
||||
|
||||
Computes cosine similarity between the query embedding and each message embedding.
|
||||
"""
|
||||
|
||||
import math
|
||||
from typing import Any, Dict, List, Optional
|
||||
|
||||
from litellm.caching.dual_cache import DualCache
|
||||
|
||||
|
||||
def _extract_content(message: dict) -> str:
|
||||
"""Extract text content from a message dict."""
|
||||
content = message.get("content", "")
|
||||
if isinstance(content, str):
|
||||
return content
|
||||
if isinstance(content, list):
|
||||
parts = []
|
||||
for part in content:
|
||||
if isinstance(part, dict) and part.get("type") == "text":
|
||||
parts.append(part.get("text", ""))
|
||||
elif isinstance(part, str):
|
||||
parts.append(part)
|
||||
return " ".join(parts)
|
||||
return ""
|
||||
|
||||
|
||||
def _truncate_text(text: str, max_chars: int = 30000) -> str:
|
||||
"""Truncate long text, keeping first and last portions."""
|
||||
if len(text) <= max_chars:
|
||||
return text
|
||||
half = max_chars // 2
|
||||
return text[:half] + "\n...\n" + text[-half:]
|
||||
|
||||
|
||||
def _cosine_similarity(a: List[float], b: List[float]) -> float:
|
||||
"""Compute cosine similarity between two vectors."""
|
||||
dot = sum(x * y for x, y in zip(a, b))
|
||||
norm_a = math.sqrt(sum(x * x for x in a))
|
||||
norm_b = math.sqrt(sum(x * x for x in b))
|
||||
if norm_a == 0 or norm_b == 0:
|
||||
return 0.0
|
||||
return dot / (norm_a * norm_b)
|
||||
|
||||
|
||||
def embedding_score_messages(
|
||||
query: str,
|
||||
messages: List[dict],
|
||||
model: str,
|
||||
cache: Optional[DualCache] = None,
|
||||
embedding_model_params: Optional[Dict[str, Any]] = None,
|
||||
) -> List[float]:
|
||||
"""
|
||||
Score each message's semantic similarity to the query using embeddings.
|
||||
|
||||
Parameters:
|
||||
query: The reference text to score against.
|
||||
messages: List of message dicts with "content" fields.
|
||||
model: The embedding model to use (e.g., "text-embedding-3-small").
|
||||
cache: Optional DualCache for cross-turn embedding caching.
|
||||
embedding_model_params: Optional additional kwargs forwarded to
|
||||
``litellm.embedding()``.
|
||||
|
||||
Returns:
|
||||
List of float scores (cosine similarity), one per message.
|
||||
"""
|
||||
import litellm
|
||||
|
||||
texts = [_truncate_text(query)]
|
||||
for msg in messages:
|
||||
texts.append(_truncate_text(_extract_content(msg)))
|
||||
|
||||
# Filter out empty texts — replace with a placeholder to maintain indexing
|
||||
processed_texts = [t if t.strip() else "empty" for t in texts]
|
||||
|
||||
kwargs: Dict[str, Any] = {
|
||||
"model": model,
|
||||
"input": processed_texts,
|
||||
"caching": cache is not None,
|
||||
}
|
||||
if embedding_model_params:
|
||||
kwargs = {**kwargs, **embedding_model_params}
|
||||
|
||||
response = litellm.embedding(**kwargs)
|
||||
|
||||
# Extract embedding vectors
|
||||
embeddings = [item["embedding"] for item in response.data]
|
||||
|
||||
query_embedding = embeddings[0]
|
||||
scores: List[float] = []
|
||||
for i in range(1, len(embeddings)):
|
||||
scores.append(_cosine_similarity(query_embedding, embeddings[i]))
|
||||
|
||||
return scores
|
||||
|
|
@ -1,6 +1,6 @@
|
|||
import os
|
||||
import sys
|
||||
from typing import List, Literal
|
||||
from typing import List, Literal, Optional
|
||||
|
||||
from litellm.litellm_core_utils.env_utils import get_env_int
|
||||
|
||||
|
|
@ -413,7 +413,20 @@ MAX_SIZE_PER_ITEM_IN_MEMORY_CACHE_IN_KB = int(
|
|||
)
|
||||
DEFAULT_MAX_TOKENS_FOR_TRITON = int(os.getenv("DEFAULT_MAX_TOKENS_FOR_TRITON", 2000))
|
||||
#### Networking settings ####
|
||||
request_timeout: float = float(os.getenv("REQUEST_TIMEOUT", 6000)) # time in seconds
|
||||
# Sentinel used when `REQUEST_TIMEOUT` is unset: `litellm.request_timeout` keeps this
|
||||
# value so longer-running surfaces (Router `timeout or litellm.request_timeout`,
|
||||
# speech/TTS, responses, vector stores, etc.) get a long HTTP deadline. Chat
|
||||
# `completion()` maps this sentinel down to 600s when the caller did not set a
|
||||
# per-request/model timeout—see ``CompletionTimeout.resolve`` in completion_timeout.py. MCP uses
|
||||
# dedicated timeouts (e.g. `MCP_CLIENT_TIMEOUT`), not `request_timeout`.
|
||||
DEFAULT_REQUEST_TIMEOUT_SECONDS: float = 6000.0
|
||||
# Pair used for default httpx clients when no custom timeout is passed: read/write
|
||||
# deadline and connect handshake (see ``http_handler`` cached handler paths).
|
||||
COMPLETION_HTTP_FALLBACK_SECONDS: float = 600.0
|
||||
HTTP_HANDLER_CONNECT_TIMEOUT_SECONDS: float = 5.0
|
||||
request_timeout: float = float(
|
||||
os.getenv("REQUEST_TIMEOUT", str(int(DEFAULT_REQUEST_TIMEOUT_SECONDS)))
|
||||
)
|
||||
DEFAULT_A2A_AGENT_TIMEOUT: float = float(
|
||||
os.getenv("DEFAULT_A2A_AGENT_TIMEOUT", 6000)
|
||||
) # 10 minutes
|
||||
|
|
@ -1060,6 +1073,9 @@ WANDB_MODELS: set = set(
|
|||
"Qwen/Qwen3-235B-A22B-Thinking-2507",
|
||||
# moonshotai
|
||||
"moonshotai/Kimi-K2-Instruct",
|
||||
"moonshotai/Kimi-K2.5",
|
||||
# MiniMaxAI
|
||||
"MiniMaxAI/MiniMax-M2.5",
|
||||
# meta models
|
||||
"meta-llama/Llama-3.1-8B-Instruct",
|
||||
"meta-llama/Llama-3.3-70B-Instruct",
|
||||
|
|
@ -1110,6 +1126,7 @@ BEDROCK_CONVERSE_MODELS = [
|
|||
"openai.gpt-oss-120b-1:0",
|
||||
"anthropic.claude-haiku-4-5-20251001-v1:0",
|
||||
"anthropic.claude-sonnet-4-5-20250929-v1:0",
|
||||
"anthropic.claude-opus-4-7",
|
||||
"anthropic.claude-opus-4-6-v1:0",
|
||||
"anthropic.claude-opus-4-6-v1",
|
||||
"anthropic.claude-sonnet-4-6",
|
||||
|
|
@ -1327,6 +1344,22 @@ BATCH_STATUS_POLL_MAX_ATTEMPTS = int(
|
|||
HEALTH_CHECK_TIMEOUT_SECONDS = int(
|
||||
os.getenv("HEALTH_CHECK_TIMEOUT_SECONDS", 60)
|
||||
) # 60 seconds
|
||||
_background_health_check_max_tokens_env = os.getenv(
|
||||
"BACKGROUND_HEALTH_CHECK_MAX_TOKENS"
|
||||
)
|
||||
try:
|
||||
_raw_background_health_check_max_tokens = (
|
||||
_background_health_check_max_tokens_env.strip()
|
||||
if _background_health_check_max_tokens_env is not None
|
||||
else ""
|
||||
)
|
||||
BACKGROUND_HEALTH_CHECK_MAX_TOKENS: Optional[int] = (
|
||||
int(_raw_background_health_check_max_tokens)
|
||||
if _raw_background_health_check_max_tokens
|
||||
else None
|
||||
)
|
||||
except (ValueError, TypeError):
|
||||
BACKGROUND_HEALTH_CHECK_MAX_TOKENS = None
|
||||
LITTELM_INTERNAL_HEALTH_SERVICE_ACCOUNT_NAME = "litellm-internal-health-check"
|
||||
LITTELM_CLI_SERVICE_ACCOUNT_NAME = "litellm-cli"
|
||||
LITELLM_INTERNAL_JOBS_SERVICE_ACCOUNT_NAME = "litellm_internal_jobs"
|
||||
|
|
|
|||
|
|
@ -58,9 +58,10 @@ from litellm.llms.lemonade.cost_calculator import (
|
|||
cost_per_token as lemonade_cost_per_token,
|
||||
)
|
||||
from litellm.llms.openai.cost_calculation import (
|
||||
_video_output_cost_per_second,
|
||||
cost_per_second as openai_cost_per_second,
|
||||
cost_per_token as openai_cost_per_token,
|
||||
)
|
||||
from litellm.llms.openai.cost_calculation import cost_per_token as openai_cost_per_token
|
||||
from litellm.llms.perplexity.cost_calculator import (
|
||||
cost_per_token as perplexity_cost_per_token,
|
||||
)
|
||||
|
|
@ -965,6 +966,8 @@ def _store_cost_breakdown_in_logging_obj(
|
|||
margin_percent: Optional[float] = None,
|
||||
margin_fixed_amount: Optional[float] = None,
|
||||
margin_total_amount: Optional[float] = None,
|
||||
cache_read_cost: Optional[float] = None,
|
||||
cache_creation_cost: Optional[float] = None,
|
||||
) -> None:
|
||||
"""
|
||||
Helper function to store cost breakdown in the logging object.
|
||||
|
|
@ -1000,6 +1003,8 @@ def _store_cost_breakdown_in_logging_obj(
|
|||
margin_percent=margin_percent,
|
||||
margin_fixed_amount=margin_fixed_amount,
|
||||
margin_total_amount=margin_total_amount,
|
||||
cache_read_cost=cache_read_cost,
|
||||
cache_creation_cost=cache_creation_cost,
|
||||
)
|
||||
|
||||
except Exception as breakdown_error:
|
||||
|
|
@ -1144,15 +1149,16 @@ def completion_cost( # noqa: PLR0915
|
|||
if isinstance(usage_obj, BaseModel) and not _is_known_usage_objects(
|
||||
usage_obj=usage_obj
|
||||
):
|
||||
_usage_for_dump = cast(BaseModel, usage_obj)
|
||||
setattr(
|
||||
completion_response,
|
||||
"usage",
|
||||
litellm.Usage(**usage_obj.model_dump()),
|
||||
litellm.Usage(**_usage_for_dump.model_dump()),
|
||||
)
|
||||
if usage_obj is None:
|
||||
_usage = {}
|
||||
elif isinstance(usage_obj, BaseModel):
|
||||
_usage = usage_obj.model_dump()
|
||||
_usage = cast(BaseModel, usage_obj).model_dump()
|
||||
else:
|
||||
_usage = usage_obj
|
||||
|
||||
|
|
@ -1279,14 +1285,20 @@ def completion_cost( # noqa: PLR0915
|
|||
_video_model_info = _metadata.get("model_info", None)
|
||||
|
||||
usage_obj = getattr(completion_response, "usage", None)
|
||||
duration_seconds: Optional[float] = None
|
||||
video_resolution: Optional[str] = None
|
||||
if completion_response is not None and usage_obj:
|
||||
# Handle both dict and Pydantic Usage object
|
||||
if isinstance(usage_obj, dict):
|
||||
duration_seconds = usage_obj.get("duration_seconds", None)
|
||||
_vr = usage_obj.get("video_resolution", None)
|
||||
else:
|
||||
duration_seconds = getattr(
|
||||
usage_obj, "duration_seconds", None
|
||||
)
|
||||
_vr = getattr(usage_obj, "video_resolution", None)
|
||||
if _vr is not None:
|
||||
video_resolution = str(_vr).strip().lower()
|
||||
|
||||
if duration_seconds is not None:
|
||||
# Calculate cost based on video duration using video-specific cost calculation
|
||||
|
|
@ -1299,6 +1311,7 @@ def completion_cost( # noqa: PLR0915
|
|||
duration_seconds=duration_seconds,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
model_info=_video_model_info,
|
||||
video_resolution=video_resolution,
|
||||
)
|
||||
# Fallback to default video cost calculation if no duration available
|
||||
return default_video_cost_calculator(
|
||||
|
|
@ -1306,6 +1319,7 @@ def completion_cost( # noqa: PLR0915
|
|||
duration_seconds=0.0, # Default to 0 if no duration available
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
model_info=_video_model_info,
|
||||
video_resolution=video_resolution,
|
||||
)
|
||||
elif call_type in _SPEECH_CALL_TYPES:
|
||||
prompt_characters = litellm.utils._count_characters(text=prompt)
|
||||
|
|
@ -1589,6 +1603,22 @@ def completion_cost( # noqa: PLR0915
|
|||
|
||||
# Store cost breakdown in logging object if available
|
||||
if litellm_logging_obj is not None:
|
||||
_cache_read_cost: Optional[float] = None
|
||||
_cache_creation_cost: Optional[float] = None
|
||||
if cost_per_token_usage_object is not None:
|
||||
_cr = getattr(cost_per_token_usage_object, "cache_read_input_tokens", None) or (cost_per_token_usage_object.model_extra or {}).get("cache_read_input_tokens")
|
||||
_cc = getattr(cost_per_token_usage_object, "cache_creation_input_tokens", None) or (cost_per_token_usage_object.model_extra or {}).get("cache_creation_input_tokens")
|
||||
if (_cr or _cc) and model:
|
||||
try:
|
||||
_mi = litellm.get_model_info(model=model, custom_llm_provider=custom_llm_provider)
|
||||
_cr_rate = _mi.get("cache_read_input_token_cost")
|
||||
if _cr and _cr_rate is not None:
|
||||
_cache_read_cost = float(_cr) * float(_cr_rate)
|
||||
_cc_rate = _mi.get("cache_creation_input_token_cost")
|
||||
if _cc and _cc_rate is not None:
|
||||
_cache_creation_cost = float(_cc) * float(_cc_rate)
|
||||
except Exception:
|
||||
pass
|
||||
_store_cost_breakdown_in_logging_obj(
|
||||
litellm_logging_obj=litellm_logging_obj,
|
||||
prompt_tokens_cost_usd_dollar=prompt_tokens_cost_usd_dollar,
|
||||
|
|
@ -1602,6 +1632,8 @@ def completion_cost( # noqa: PLR0915
|
|||
margin_percent=margin_percent,
|
||||
margin_fixed_amount=margin_fixed_amount,
|
||||
margin_total_amount=margin_total_amount,
|
||||
cache_read_cost=_cache_read_cost,
|
||||
cache_creation_cost=_cache_creation_cost,
|
||||
)
|
||||
|
||||
return _final_cost
|
||||
|
|
@ -1626,7 +1658,7 @@ def get_response_cost_from_hidden_params(
|
|||
hidden_params: Union[dict, BaseModel],
|
||||
) -> Optional[float]:
|
||||
if isinstance(hidden_params, BaseModel):
|
||||
_hidden_params_dict = hidden_params.model_dump()
|
||||
_hidden_params_dict = cast(BaseModel, hidden_params).model_dump()
|
||||
else:
|
||||
_hidden_params_dict = hidden_params
|
||||
|
||||
|
|
@ -1963,6 +1995,7 @@ def default_video_cost_calculator(
|
|||
duration_seconds: float,
|
||||
custom_llm_provider: Optional[str] = None,
|
||||
model_info: Optional[ModelInfo] = None,
|
||||
video_resolution: Optional[str] = None,
|
||||
) -> float:
|
||||
"""
|
||||
Default video cost calculator for video generation
|
||||
|
|
@ -1974,6 +2007,7 @@ def default_video_cost_calculator(
|
|||
model_info (Optional[ModelInfo]): Deployment-level model info containing
|
||||
custom video pricing. When provided, used before falling back to
|
||||
the global litellm.model_cost lookup.
|
||||
video_resolution (Optional[str]): From usage (e.g. ``720p``, ``1080p``) for tiered per-second pricing.
|
||||
|
||||
Returns:
|
||||
float: Cost in USD for the video generation
|
||||
|
|
@ -2027,8 +2061,7 @@ def default_video_cost_calculator(
|
|||
if video_cost_per_second is not None:
|
||||
return video_cost_per_second * duration_seconds
|
||||
|
||||
# Fallback to general output cost per second
|
||||
output_cost_per_second = cost_info.get("output_cost_per_second")
|
||||
output_cost_per_second = _video_output_cost_per_second(cost_info, video_resolution)
|
||||
if output_cost_per_second is not None:
|
||||
return output_cost_per_second * duration_seconds
|
||||
|
||||
|
|
|
|||
|
|
@ -221,6 +221,7 @@ class MCPClient:
|
|||
self.extra_headers: Optional[Dict[str, str]] = extra_headers
|
||||
self.ssl_verify: Optional[VerifyTypes] = ssl_verify
|
||||
self._aws_auth: Optional[httpx.Auth] = aws_auth
|
||||
self._last_initialize_instructions: Optional[str] = None
|
||||
# handle the basic auth value if provided
|
||||
if auth_value:
|
||||
self.update_auth_value(auth_value)
|
||||
|
|
@ -296,7 +297,12 @@ class MCPClient:
|
|||
session_ctx = ClientSession(read_stream, write_stream)
|
||||
session = await session_ctx.__aenter__()
|
||||
try:
|
||||
await session.initialize()
|
||||
init_result = await session.initialize()
|
||||
self._last_initialize_instructions = None
|
||||
if init_result is not None:
|
||||
ins = getattr(init_result, "instructions", None)
|
||||
if isinstance(ins, str) and ins.strip():
|
||||
self._last_initialize_instructions = ins.strip()
|
||||
return await operation(session)
|
||||
finally:
|
||||
try:
|
||||
|
|
@ -315,6 +321,7 @@ class MCPClient:
|
|||
"""Open a session, run the provided coroutine, and clean up."""
|
||||
http_client: Optional[httpx.AsyncClient] = None
|
||||
try:
|
||||
self._last_initialize_instructions = None
|
||||
transport_ctx, http_client = self._create_transport_context()
|
||||
return await self._execute_session_operation(transport_ctx, operation)
|
||||
except Exception:
|
||||
|
|
|
|||
|
|
@ -16,6 +16,7 @@ For batching specific details see CustomBatchLogger class
|
|||
import asyncio
|
||||
import datetime
|
||||
import os
|
||||
import time
|
||||
import traceback
|
||||
from datetime import datetime as datetimeObj
|
||||
from typing import Any, Dict, List, Optional, Union
|
||||
|
|
@ -301,7 +302,7 @@ class DataDogLogger(
|
|||
self.log_queue.append(dd_payload)
|
||||
|
||||
if len(self.log_queue) >= self.batch_size:
|
||||
await self.async_send_batch()
|
||||
await self.flush_queue()
|
||||
except Exception as e:
|
||||
verbose_logger.exception(
|
||||
f"Datadog: async_post_call_failure_hook - {str(e)}\n{traceback.format_exc()}"
|
||||
|
|
@ -324,9 +325,12 @@ class DataDogLogger(
|
|||
verbose_logger.exception("Datadog: log_queue does not exist")
|
||||
return
|
||||
|
||||
batch_to_send = self.log_queue[:]
|
||||
self.log_queue = []
|
||||
|
||||
verbose_logger.debug(
|
||||
"Datadog - about to flush %s events on %s",
|
||||
len(self.log_queue),
|
||||
len(batch_to_send),
|
||||
self.intake_url,
|
||||
)
|
||||
|
||||
|
|
@ -335,9 +339,10 @@ class DataDogLogger(
|
|||
"[DATADOG MOCK] Mock mode enabled - API calls will be intercepted"
|
||||
)
|
||||
|
||||
response = await self.async_send_compressed_data(self.log_queue)
|
||||
response = await self.async_send_compressed_data(batch_to_send)
|
||||
if response.status_code == 413:
|
||||
verbose_logger.exception(DD_ERRORS.DATADOG_413_ERROR.value)
|
||||
self.log_queue = batch_to_send + self.log_queue
|
||||
return
|
||||
|
||||
response.raise_for_status()
|
||||
|
|
@ -348,7 +353,7 @@ class DataDogLogger(
|
|||
|
||||
if self.is_mock_mode:
|
||||
verbose_logger.debug(
|
||||
f"[DATADOG MOCK] Batch of {len(self.log_queue)} events successfully mocked"
|
||||
f"[DATADOG MOCK] Batch of {len(batch_to_send)} events successfully mocked"
|
||||
)
|
||||
else:
|
||||
verbose_logger.debug(
|
||||
|
|
@ -356,11 +361,26 @@ class DataDogLogger(
|
|||
response.status_code,
|
||||
response.text,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
self.log_queue = batch_to_send + self.log_queue
|
||||
verbose_logger.exception(
|
||||
f"Datadog Error sending batch API - {str(e)}\n{traceback.format_exc()}"
|
||||
)
|
||||
|
||||
async def flush_queue(self):
|
||||
if self.flush_lock is None:
|
||||
return
|
||||
|
||||
async with self.flush_lock:
|
||||
if self.log_queue:
|
||||
verbose_logger.debug(
|
||||
"Datadog: Flushing batch of %s events", len(self.log_queue)
|
||||
)
|
||||
await self.async_send_batch()
|
||||
if not self.log_queue:
|
||||
self.last_flush_time = time.time()
|
||||
|
||||
def log_success_event(self, kwargs, response_obj, start_time, end_time):
|
||||
"""
|
||||
Sync Log success events to Datadog
|
||||
|
|
@ -429,7 +449,7 @@ class DataDogLogger(
|
|||
)
|
||||
|
||||
if len(self.log_queue) >= self.batch_size:
|
||||
await self.async_send_batch()
|
||||
await self.flush_queue()
|
||||
|
||||
def _create_datadog_logging_payload_helper(
|
||||
self,
|
||||
|
|
|
|||
|
|
@ -404,11 +404,14 @@ class S3Logger(CustomBatchLogger, BaseAWSLLM):
|
|||
# Prepare the signed headers
|
||||
signed_headers = dict(aws_request.headers.items())
|
||||
|
||||
# Use prepared URL so path segments match SigV4 canonical request (e.g. %20 for spaces).
|
||||
request_url = prepped.url or url
|
||||
|
||||
# Make the request with retry for transient S3 errors (500/503)
|
||||
max_retries = 3
|
||||
for attempt in range(max_retries):
|
||||
response = await self.async_httpx_client.put(
|
||||
url, data=json_string, headers=signed_headers
|
||||
request_url, data=json_string, headers=signed_headers
|
||||
)
|
||||
if response.status_code in (500, 503) and attempt < max_retries - 1:
|
||||
wait_time = 2**attempt # 1s, 2s
|
||||
|
|
@ -590,6 +593,9 @@ class S3Logger(CustomBatchLogger, BaseAWSLLM):
|
|||
# Prepare the signed headers
|
||||
signed_headers = dict(aws_request.headers.items())
|
||||
|
||||
# Use prepared URL so path segments match SigV4 canonical request (e.g. %20 for spaces).
|
||||
request_url = prepped.url or url
|
||||
|
||||
httpx_client = _get_httpx_client(
|
||||
params={"ssl_verify": self.s3_verify}
|
||||
if self.s3_verify is not None
|
||||
|
|
@ -599,7 +605,7 @@ class S3Logger(CustomBatchLogger, BaseAWSLLM):
|
|||
max_retries = 3
|
||||
for attempt in range(max_retries):
|
||||
response = httpx_client.put(
|
||||
url, data=json_string, headers=signed_headers
|
||||
request_url, data=json_string, headers=signed_headers
|
||||
)
|
||||
if response.status_code in (500, 503) and attempt < max_retries - 1:
|
||||
wait_time = 2**attempt # 1s, 2s
|
||||
|
|
@ -701,8 +707,10 @@ class S3Logger(CustomBatchLogger, BaseAWSLLM):
|
|||
# Prepare the signed headers
|
||||
signed_headers = dict(aws_request.headers.items())
|
||||
|
||||
# Make the request
|
||||
response = await self.async_httpx_client.get(url, headers=signed_headers)
|
||||
request_url = prepped.url or url
|
||||
response = await self.async_httpx_client.get(
|
||||
request_url, headers=signed_headers
|
||||
)
|
||||
|
||||
if response.status_code != 200:
|
||||
verbose_logger.exception(
|
||||
|
|
|
|||
83
litellm/litellm_core_utils/completion_timeout.py
Normal file
83
litellm/litellm_core_utils/completion_timeout.py
Normal file
|
|
@ -0,0 +1,83 @@
|
|||
"""Completion HTTP timeout resolution (kept out of ``main.py`` to limit import cycles)."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Callable, Optional, Union
|
||||
|
||||
import httpx
|
||||
|
||||
from litellm.constants import (
|
||||
COMPLETION_HTTP_FALLBACK_SECONDS,
|
||||
DEFAULT_REQUEST_TIMEOUT_SECONDS,
|
||||
)
|
||||
|
||||
|
||||
class CompletionTimeout:
|
||||
"""Resolves HTTP timeout for ``completion()`` from model vs global settings."""
|
||||
|
||||
@staticmethod
|
||||
def _fallback_when_no_explicit_timeout(
|
||||
global_timeout: Optional[Union[float, str]],
|
||||
) -> float:
|
||||
"""
|
||||
Used when ``model_timeout`` and kwargs timeouts are all unset.
|
||||
|
||||
``global_timeout`` is :attr:`litellm.request_timeout` (numeric / string), not
|
||||
:class:`httpx.Timeout`.
|
||||
|
||||
If it equals :data:`~litellm.constants.DEFAULT_REQUEST_TIMEOUT_SECONDS` (6000),
|
||||
return :data:`~litellm.constants.COMPLETION_HTTP_FALLBACK_SECONDS`. Same if
|
||||
``None``. Otherwise return ``float(global_timeout)``.
|
||||
"""
|
||||
if global_timeout is None:
|
||||
return COMPLETION_HTTP_FALLBACK_SECONDS
|
||||
if float(global_timeout) == float(DEFAULT_REQUEST_TIMEOUT_SECONDS):
|
||||
return COMPLETION_HTTP_FALLBACK_SECONDS
|
||||
return float(global_timeout)
|
||||
|
||||
@staticmethod
|
||||
def resolve(
|
||||
model_timeout: Optional[Union[float, str, httpx.Timeout]],
|
||||
kwargs: dict,
|
||||
custom_llm_provider: str,
|
||||
*,
|
||||
global_timeout: Optional[Union[float, str]],
|
||||
supports_httpx_timeout: Callable[[str], bool],
|
||||
) -> Union[float, httpx.Timeout]:
|
||||
"""
|
||||
Resolution order (first non-None wins):
|
||||
|
||||
1. ``model_timeout`` (call argument / merged ``litellm_params``)
|
||||
2. ``kwargs["timeout"]``
|
||||
3. ``kwargs["request_timeout"]``
|
||||
4. Fallback from ``global_timeout`` (:attr:`litellm.request_timeout`) — if it is
|
||||
the package default (6000), use 600 instead.
|
||||
|
||||
Coerce :class:`httpx.Timeout` when the provider does not support it.
|
||||
Explicit ``6000`` on the model or in kwargs is kept as ``6000``.
|
||||
"""
|
||||
resolved: Union[float, str, httpx.Timeout]
|
||||
if model_timeout is not None:
|
||||
resolved = model_timeout
|
||||
elif kwargs.get("timeout") is not None:
|
||||
resolved = kwargs["timeout"]
|
||||
elif kwargs.get("request_timeout") is not None:
|
||||
resolved = kwargs["request_timeout"]
|
||||
else:
|
||||
resolved = CompletionTimeout._fallback_when_no_explicit_timeout(
|
||||
global_timeout
|
||||
)
|
||||
|
||||
if isinstance(resolved, httpx.Timeout) and not supports_httpx_timeout(
|
||||
custom_llm_provider
|
||||
):
|
||||
read_timeout = resolved.read
|
||||
resolved = (
|
||||
float(read_timeout)
|
||||
if read_timeout is not None
|
||||
else COMPLETION_HTTP_FALLBACK_SECONDS
|
||||
) # default 10 min timeout
|
||||
elif not isinstance(resolved, httpx.Timeout):
|
||||
resolved = float(resolved) # type: ignore
|
||||
|
||||
return resolved
|
||||
|
|
@ -6,7 +6,7 @@ from typing import Any, Optional
|
|||
import httpx
|
||||
|
||||
import litellm
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm._logging import _redact_string, verbose_logger
|
||||
from litellm.types.utils import LlmProviders
|
||||
|
||||
from ..exceptions import (
|
||||
|
|
@ -2304,7 +2304,7 @@ def exception_type( # type: ignore # noqa: PLR0915
|
|||
else:
|
||||
# if no status code then it is an APIConnectionError: https://github.com/openai/openai-python#handling-errors
|
||||
raise APIConnectionError(
|
||||
message=f"{exception_provider} APIConnectionError - {message}\n{traceback.format_exc()}",
|
||||
message=f"{exception_provider} APIConnectionError - {message}\n{_redact_string(traceback.format_exc())}",
|
||||
llm_provider="azure",
|
||||
model=model,
|
||||
litellm_debug_info=extra_information,
|
||||
|
|
@ -2431,7 +2431,7 @@ def exception_type( # type: ignore # noqa: PLR0915
|
|||
else:
|
||||
raise APIConnectionError(
|
||||
message="{}\n{}".format(
|
||||
str(original_exception), traceback.format_exc()
|
||||
str(original_exception), _redact_string(traceback.format_exc())
|
||||
),
|
||||
llm_provider=custom_llm_provider,
|
||||
model=model,
|
||||
|
|
@ -2460,7 +2460,7 @@ def exception_type( # type: ignore # noqa: PLR0915
|
|||
setattr(e, "litellm_response_headers", litellm_response_headers)
|
||||
raise e # it's already mapped
|
||||
raised_exc = APIConnectionError(
|
||||
message="{}\n{}".format(original_exception, traceback.format_exc()),
|
||||
message="{}\n{}".format(original_exception, _redact_string(traceback.format_exc())),
|
||||
llm_provider="",
|
||||
model="",
|
||||
)
|
||||
|
|
|
|||
|
|
@ -36,7 +36,7 @@ from litellm import (
|
|||
log_raw_request_response,
|
||||
turn_off_message_logging,
|
||||
)
|
||||
from litellm._logging import _is_debugging_on, verbose_logger
|
||||
from litellm._logging import _is_debugging_on, _redact_string, verbose_logger
|
||||
from litellm._uuid import uuid
|
||||
from litellm.batches.batch_utils import _handle_completed_batch
|
||||
from litellm.caching.caching import DualCache, InMemoryCache
|
||||
|
|
@ -354,9 +354,9 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
)
|
||||
self.function_id = function_id
|
||||
self.streaming_chunks: List[Any] = [] # for generating complete stream response
|
||||
self.sync_streaming_chunks: List[
|
||||
Any
|
||||
] = [] # for generating complete stream response
|
||||
self.sync_streaming_chunks: List[Any] = (
|
||||
[]
|
||||
) # for generating complete stream response
|
||||
self.log_raw_request_response = log_raw_request_response
|
||||
|
||||
# Initialize dynamic callbacks
|
||||
|
|
@ -811,9 +811,9 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
prompt_spec=prompt_spec,
|
||||
dynamic_callback_params=dynamic_callback_params,
|
||||
):
|
||||
self.model_call_details[
|
||||
"prompt_integration"
|
||||
] = logger.__class__.__name__
|
||||
self.model_call_details["prompt_integration"] = (
|
||||
logger.__class__.__name__
|
||||
)
|
||||
return logger
|
||||
except Exception:
|
||||
# If check fails, continue to next logger
|
||||
|
|
@ -881,9 +881,9 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
if anthropic_cache_control_logger := AnthropicCacheControlHook.get_custom_logger_for_anthropic_cache_control_hook(
|
||||
non_default_params
|
||||
):
|
||||
self.model_call_details[
|
||||
"prompt_integration"
|
||||
] = anthropic_cache_control_logger.__class__.__name__
|
||||
self.model_call_details["prompt_integration"] = (
|
||||
anthropic_cache_control_logger.__class__.__name__
|
||||
)
|
||||
return anthropic_cache_control_logger
|
||||
|
||||
#########################################################
|
||||
|
|
@ -895,9 +895,9 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
internal_usage_cache=None,
|
||||
llm_router=None,
|
||||
)
|
||||
self.model_call_details[
|
||||
"prompt_integration"
|
||||
] = vector_store_custom_logger.__class__.__name__
|
||||
self.model_call_details["prompt_integration"] = (
|
||||
vector_store_custom_logger.__class__.__name__
|
||||
)
|
||||
# Add to global callbacks so post-call hooks are invoked
|
||||
if (
|
||||
vector_store_custom_logger
|
||||
|
|
@ -957,9 +957,9 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
model
|
||||
): # if model name was changes pre-call, overwrite the initial model call name with the new one
|
||||
self.model_call_details["model"] = model
|
||||
self.model_call_details["litellm_params"][
|
||||
"api_base"
|
||||
] = self._get_masked_api_base(additional_args.get("api_base", ""))
|
||||
self.model_call_details["litellm_params"]["api_base"] = (
|
||||
self._get_masked_api_base(additional_args.get("api_base", ""))
|
||||
)
|
||||
|
||||
def pre_call(self, input, api_key, model=None, additional_args={}): # noqa: PLR0915
|
||||
# Log the exact input to the LLM API
|
||||
|
|
@ -988,10 +988,10 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
try:
|
||||
# [Non-blocking Extra Debug Information in metadata]
|
||||
if turn_off_message_logging is True:
|
||||
_metadata[
|
||||
"raw_request"
|
||||
] = "redacted by litellm. \
|
||||
_metadata["raw_request"] = (
|
||||
"redacted by litellm. \
|
||||
'litellm.turn_off_message_logging=True'"
|
||||
)
|
||||
else:
|
||||
curl_command = self._get_request_curl_command(
|
||||
api_base=additional_args.get("api_base", ""),
|
||||
|
|
@ -1002,34 +1002,34 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
|
||||
_metadata["raw_request"] = str(curl_command)
|
||||
# split up, so it's easier to parse in the UI
|
||||
self.model_call_details[
|
||||
"raw_request_typed_dict"
|
||||
] = RawRequestTypedDict(
|
||||
raw_request_api_base=str(
|
||||
additional_args.get("api_base") or ""
|
||||
),
|
||||
raw_request_body=self._get_raw_request_body(
|
||||
additional_args.get("complete_input_dict", {})
|
||||
),
|
||||
# NOTE: setting ignore_sensitive_headers to True will cause
|
||||
# the Authorization header to be leaked when calls to the health
|
||||
# endpoint are made and fail.
|
||||
raw_request_headers=self._get_masked_headers(
|
||||
additional_args.get("headers", {}) or {},
|
||||
),
|
||||
error=None,
|
||||
self.model_call_details["raw_request_typed_dict"] = (
|
||||
RawRequestTypedDict(
|
||||
raw_request_api_base=str(
|
||||
additional_args.get("api_base") or ""
|
||||
),
|
||||
raw_request_body=self._get_raw_request_body(
|
||||
additional_args.get("complete_input_dict", {})
|
||||
),
|
||||
# NOTE: setting ignore_sensitive_headers to True will cause
|
||||
# the Authorization header to be leaked when calls to the health
|
||||
# endpoint are made and fail.
|
||||
raw_request_headers=self._get_masked_headers(
|
||||
additional_args.get("headers", {}) or {},
|
||||
),
|
||||
error=None,
|
||||
)
|
||||
)
|
||||
except Exception as e:
|
||||
self.model_call_details[
|
||||
"raw_request_typed_dict"
|
||||
] = RawRequestTypedDict(
|
||||
error=str(e),
|
||||
self.model_call_details["raw_request_typed_dict"] = (
|
||||
RawRequestTypedDict(
|
||||
error=str(e),
|
||||
)
|
||||
)
|
||||
_metadata[
|
||||
"raw_request"
|
||||
] = "Unable to Log \
|
||||
_metadata["raw_request"] = (
|
||||
"Unable to Log \
|
||||
raw request: {}".format(
|
||||
str(e)
|
||||
str(e)
|
||||
)
|
||||
)
|
||||
if getattr(self, "logger_fn", None) and callable(self.logger_fn):
|
||||
try:
|
||||
|
|
@ -1330,13 +1330,13 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
for callback in callbacks:
|
||||
try:
|
||||
if isinstance(callback, CustomLogger):
|
||||
response: Optional[
|
||||
MCPPostCallResponseObject
|
||||
] = await callback.async_post_mcp_tool_call_hook(
|
||||
kwargs=kwargs,
|
||||
response_obj=post_mcp_tool_call_response_obj,
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
response: Optional[MCPPostCallResponseObject] = (
|
||||
await callback.async_post_mcp_tool_call_hook(
|
||||
kwargs=kwargs,
|
||||
response_obj=post_mcp_tool_call_response_obj,
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
)
|
||||
)
|
||||
######################################################################
|
||||
# if any of the callbacks modify the response, use the modified response
|
||||
|
|
@ -1387,6 +1387,8 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
margin_percent: Optional[float] = None,
|
||||
margin_fixed_amount: Optional[float] = None,
|
||||
margin_total_amount: Optional[float] = None,
|
||||
cache_read_cost: Optional[float] = None,
|
||||
cache_creation_cost: Optional[float] = None,
|
||||
) -> None:
|
||||
"""
|
||||
Helper method to store cost breakdown in the logging object.
|
||||
|
|
@ -1411,6 +1413,10 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
total_cost=total_cost,
|
||||
tool_usage_cost=cost_for_built_in_tools_cost_usd_dollar,
|
||||
)
|
||||
if cache_read_cost is not None and cache_read_cost > 0:
|
||||
self.cost_breakdown["cache_read_cost"] = cache_read_cost
|
||||
if cache_creation_cost is not None and cache_creation_cost > 0:
|
||||
self.cost_breakdown["cache_creation_cost"] = cache_creation_cost
|
||||
|
||||
# Store additional costs if provided (free-form dict for extensibility)
|
||||
if (
|
||||
|
|
@ -1537,9 +1543,9 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
verbose_logger.debug(
|
||||
f"response_cost_failure_debug_information: {debug_info}"
|
||||
)
|
||||
self.model_call_details[
|
||||
"response_cost_failure_debug_information"
|
||||
] = debug_info
|
||||
self.model_call_details["response_cost_failure_debug_information"] = (
|
||||
debug_info
|
||||
)
|
||||
return None
|
||||
|
||||
try:
|
||||
|
|
@ -1565,9 +1571,9 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
verbose_logger.debug(
|
||||
f"response_cost_failure_debug_information: {debug_info}"
|
||||
)
|
||||
self.model_call_details[
|
||||
"response_cost_failure_debug_information"
|
||||
] = debug_info
|
||||
self.model_call_details["response_cost_failure_debug_information"] = (
|
||||
debug_info
|
||||
)
|
||||
|
||||
return None
|
||||
|
||||
|
|
@ -1716,9 +1722,9 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
self.model_call_details["litellm_params"].setdefault("metadata", {})
|
||||
if self.model_call_details["litellm_params"]["metadata"] is None:
|
||||
self.model_call_details["litellm_params"]["metadata"] = {}
|
||||
self.model_call_details["litellm_params"]["metadata"][
|
||||
"hidden_params"
|
||||
] = getattr(logging_result, "_hidden_params", {})
|
||||
self.model_call_details["litellm_params"]["metadata"]["hidden_params"] = (
|
||||
getattr(logging_result, "_hidden_params", {})
|
||||
)
|
||||
|
||||
def _process_hidden_params_and_response_cost(
|
||||
self,
|
||||
|
|
@ -1747,9 +1753,9 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
result=logging_result
|
||||
)
|
||||
|
||||
self.model_call_details[
|
||||
"standard_logging_object"
|
||||
] = self._build_standard_logging_payload(logging_result, start_time, end_time)
|
||||
self.model_call_details["standard_logging_object"] = (
|
||||
self._build_standard_logging_payload(logging_result, start_time, end_time)
|
||||
)
|
||||
|
||||
if (
|
||||
standard_logging_payload := self.model_call_details.get(
|
||||
|
|
@ -1827,9 +1833,9 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
end_time = datetime.datetime.now()
|
||||
if self.completion_start_time is None:
|
||||
self.completion_start_time = end_time
|
||||
self.model_call_details[
|
||||
"completion_start_time"
|
||||
] = self.completion_start_time
|
||||
self.model_call_details["completion_start_time"] = (
|
||||
self.completion_start_time
|
||||
)
|
||||
|
||||
self.model_call_details["log_event_type"] = "successful_api_call"
|
||||
self.model_call_details["end_time"] = end_time
|
||||
|
|
@ -1866,10 +1872,10 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
end_time=end_time,
|
||||
)
|
||||
elif isinstance(result, dict) or isinstance(result, list):
|
||||
self.model_call_details[
|
||||
"standard_logging_object"
|
||||
] = self._build_standard_logging_payload(
|
||||
result, start_time, end_time
|
||||
self.model_call_details["standard_logging_object"] = (
|
||||
self._build_standard_logging_payload(
|
||||
result, start_time, end_time
|
||||
)
|
||||
)
|
||||
if (
|
||||
standard_logging_payload := self.model_call_details.get(
|
||||
|
|
@ -1878,9 +1884,9 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
) is not None:
|
||||
emit_standard_logging_payload(standard_logging_payload)
|
||||
elif standard_logging_object is not None:
|
||||
self.model_call_details[
|
||||
"standard_logging_object"
|
||||
] = standard_logging_object
|
||||
self.model_call_details["standard_logging_object"] = (
|
||||
standard_logging_object
|
||||
)
|
||||
else:
|
||||
self.model_call_details["response_cost"] = None
|
||||
|
||||
|
|
@ -2038,20 +2044,20 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
verbose_logger.debug(
|
||||
"Logging Details LiteLLM-Success Call streaming complete"
|
||||
)
|
||||
self.model_call_details[
|
||||
"complete_streaming_response"
|
||||
] = complete_streaming_response
|
||||
self.model_call_details[
|
||||
"response_cost"
|
||||
] = self._response_cost_calculator(result=complete_streaming_response)
|
||||
self.model_call_details["complete_streaming_response"] = (
|
||||
complete_streaming_response
|
||||
)
|
||||
self.model_call_details["response_cost"] = (
|
||||
self._response_cost_calculator(result=complete_streaming_response)
|
||||
)
|
||||
self._merge_hidden_params_from_response_into_metadata(
|
||||
complete_streaming_response
|
||||
)
|
||||
## STANDARDIZED LOGGING PAYLOAD
|
||||
self.model_call_details[
|
||||
"standard_logging_object"
|
||||
] = self._build_standard_logging_payload(
|
||||
complete_streaming_response, start_time, end_time
|
||||
self.model_call_details["standard_logging_object"] = (
|
||||
self._build_standard_logging_payload(
|
||||
complete_streaming_response, start_time, end_time
|
||||
)
|
||||
)
|
||||
if (
|
||||
standard_logging_payload := self.model_call_details.get(
|
||||
|
|
@ -2385,10 +2391,10 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
)
|
||||
else:
|
||||
if self.stream and complete_streaming_response:
|
||||
self.model_call_details[
|
||||
"complete_response"
|
||||
] = self.model_call_details.get(
|
||||
"complete_streaming_response", {}
|
||||
self.model_call_details["complete_response"] = (
|
||||
self.model_call_details.get(
|
||||
"complete_streaming_response", {}
|
||||
)
|
||||
)
|
||||
result = self.model_call_details["complete_response"]
|
||||
openMeterLogger.log_success_event(
|
||||
|
|
@ -2412,10 +2418,10 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
)
|
||||
else:
|
||||
if self.stream and complete_streaming_response:
|
||||
self.model_call_details[
|
||||
"complete_response"
|
||||
] = self.model_call_details.get(
|
||||
"complete_streaming_response", {}
|
||||
self.model_call_details["complete_response"] = (
|
||||
self.model_call_details.get(
|
||||
"complete_streaming_response", {}
|
||||
)
|
||||
)
|
||||
result = self.model_call_details["complete_response"]
|
||||
|
||||
|
|
@ -2554,9 +2560,9 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
if complete_streaming_response is not None:
|
||||
print_verbose("Async success callbacks: Got a complete streaming response")
|
||||
|
||||
self.model_call_details[
|
||||
"async_complete_streaming_response"
|
||||
] = complete_streaming_response
|
||||
self.model_call_details["async_complete_streaming_response"] = (
|
||||
complete_streaming_response
|
||||
)
|
||||
|
||||
try:
|
||||
if self.model_call_details.get("cache_hit", False) is True:
|
||||
|
|
@ -2567,10 +2573,10 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
model_call_details=self.model_call_details
|
||||
)
|
||||
# base_model defaults to None if not set on model_info
|
||||
self.model_call_details[
|
||||
"response_cost"
|
||||
] = self._response_cost_calculator(
|
||||
result=complete_streaming_response
|
||||
self.model_call_details["response_cost"] = (
|
||||
self._response_cost_calculator(
|
||||
result=complete_streaming_response
|
||||
)
|
||||
)
|
||||
|
||||
verbose_logger.debug(
|
||||
|
|
@ -2587,10 +2593,10 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
)
|
||||
|
||||
## STANDARDIZED LOGGING PAYLOAD
|
||||
self.model_call_details[
|
||||
"standard_logging_object"
|
||||
] = self._build_standard_logging_payload(
|
||||
complete_streaming_response, start_time, end_time
|
||||
self.model_call_details["standard_logging_object"] = (
|
||||
self._build_standard_logging_payload(
|
||||
complete_streaming_response, start_time, end_time
|
||||
)
|
||||
)
|
||||
|
||||
# print standard logging payload
|
||||
|
|
@ -2617,9 +2623,9 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
# _success_handler_helper_fn
|
||||
if self.model_call_details.get("standard_logging_object") is None:
|
||||
## STANDARDIZED LOGGING PAYLOAD
|
||||
self.model_call_details[
|
||||
"standard_logging_object"
|
||||
] = self._build_standard_logging_payload(result, start_time, end_time)
|
||||
self.model_call_details["standard_logging_object"] = (
|
||||
self._build_standard_logging_payload(result, start_time, end_time)
|
||||
)
|
||||
|
||||
# print standard logging payload
|
||||
if (
|
||||
|
|
@ -2848,7 +2854,11 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
|
||||
self.model_call_details["log_event_type"] = "failed_api_call"
|
||||
self.model_call_details["exception"] = exception
|
||||
self.model_call_details["traceback_exception"] = traceback_exception
|
||||
self.model_call_details["traceback_exception"] = (
|
||||
_redact_string(traceback_exception)
|
||||
if isinstance(traceback_exception, str)
|
||||
else traceback_exception
|
||||
)
|
||||
self.model_call_details["end_time"] = end_time
|
||||
self.model_call_details.setdefault("original_response", None)
|
||||
self.model_call_details["response_cost"] = 0
|
||||
|
|
@ -2862,18 +2872,18 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
|
||||
## STANDARDIZED LOGGING PAYLOAD
|
||||
|
||||
self.model_call_details[
|
||||
"standard_logging_object"
|
||||
] = get_standard_logging_object_payload(
|
||||
kwargs=self.model_call_details,
|
||||
init_response_obj={},
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
logging_obj=self,
|
||||
status="failure",
|
||||
error_str=str(exception),
|
||||
original_exception=exception,
|
||||
standard_built_in_tools_params=self.standard_built_in_tools_params,
|
||||
self.model_call_details["standard_logging_object"] = (
|
||||
get_standard_logging_object_payload(
|
||||
kwargs=self.model_call_details,
|
||||
init_response_obj={},
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
logging_obj=self,
|
||||
status="failure",
|
||||
error_str=_redact_string(str(exception)),
|
||||
original_exception=exception,
|
||||
standard_built_in_tools_params=self.standard_built_in_tools_params,
|
||||
)
|
||||
)
|
||||
return start_time, end_time
|
||||
|
||||
|
|
@ -3843,9 +3853,9 @@ def _init_custom_logger_compatible_class( # noqa: PLR0915
|
|||
service_name=arize_config.project_name,
|
||||
)
|
||||
|
||||
os.environ[
|
||||
"OTEL_EXPORTER_OTLP_TRACES_HEADERS"
|
||||
] = f"space_id={arize_config.space_key or arize_config.space_id},api_key={arize_config.api_key}"
|
||||
os.environ["OTEL_EXPORTER_OTLP_TRACES_HEADERS"] = (
|
||||
f"space_id={arize_config.space_key or arize_config.space_id},api_key={arize_config.api_key}"
|
||||
)
|
||||
for callback in _in_memory_loggers:
|
||||
if (
|
||||
isinstance(callback, ArizeLogger)
|
||||
|
|
@ -3871,13 +3881,13 @@ def _init_custom_logger_compatible_class( # noqa: PLR0915
|
|||
existing_attrs = os.environ.get("OTEL_RESOURCE_ATTRIBUTES", "")
|
||||
# Add openinference.project.name attribute
|
||||
if existing_attrs:
|
||||
os.environ[
|
||||
"OTEL_RESOURCE_ATTRIBUTES"
|
||||
] = f"{existing_attrs},openinference.project.name={arize_phoenix_config.project_name}"
|
||||
os.environ["OTEL_RESOURCE_ATTRIBUTES"] = (
|
||||
f"{existing_attrs},openinference.project.name={arize_phoenix_config.project_name}"
|
||||
)
|
||||
else:
|
||||
os.environ[
|
||||
"OTEL_RESOURCE_ATTRIBUTES"
|
||||
] = f"openinference.project.name={arize_phoenix_config.project_name}"
|
||||
os.environ["OTEL_RESOURCE_ATTRIBUTES"] = (
|
||||
f"openinference.project.name={arize_phoenix_config.project_name}"
|
||||
)
|
||||
|
||||
# Set Phoenix project name from environment variable
|
||||
phoenix_project_name = os.environ.get("PHOENIX_PROJECT_NAME", None)
|
||||
|
|
@ -3885,19 +3895,19 @@ def _init_custom_logger_compatible_class( # noqa: PLR0915
|
|||
existing_attrs = os.environ.get("OTEL_RESOURCE_ATTRIBUTES", "")
|
||||
# Add openinference.project.name attribute
|
||||
if existing_attrs:
|
||||
os.environ[
|
||||
"OTEL_RESOURCE_ATTRIBUTES"
|
||||
] = f"{existing_attrs},openinference.project.name={phoenix_project_name}"
|
||||
os.environ["OTEL_RESOURCE_ATTRIBUTES"] = (
|
||||
f"{existing_attrs},openinference.project.name={phoenix_project_name}"
|
||||
)
|
||||
else:
|
||||
os.environ[
|
||||
"OTEL_RESOURCE_ATTRIBUTES"
|
||||
] = f"openinference.project.name={phoenix_project_name}"
|
||||
os.environ["OTEL_RESOURCE_ATTRIBUTES"] = (
|
||||
f"openinference.project.name={phoenix_project_name}"
|
||||
)
|
||||
|
||||
# auth can be disabled on local deployments of arize phoenix
|
||||
if arize_phoenix_config.otlp_auth_headers is not None:
|
||||
os.environ[
|
||||
"OTEL_EXPORTER_OTLP_TRACES_HEADERS"
|
||||
] = arize_phoenix_config.otlp_auth_headers
|
||||
os.environ["OTEL_EXPORTER_OTLP_TRACES_HEADERS"] = (
|
||||
arize_phoenix_config.otlp_auth_headers
|
||||
)
|
||||
|
||||
for callback in _in_memory_loggers:
|
||||
if (
|
||||
|
|
@ -4084,9 +4094,9 @@ def _init_custom_logger_compatible_class( # noqa: PLR0915
|
|||
exporter="otlp_http",
|
||||
endpoint="https://langtrace.ai/api/trace",
|
||||
)
|
||||
os.environ[
|
||||
"OTEL_EXPORTER_OTLP_TRACES_HEADERS"
|
||||
] = f"api_key={os.getenv('LANGTRACE_API_KEY')}"
|
||||
os.environ["OTEL_EXPORTER_OTLP_TRACES_HEADERS"] = (
|
||||
f"api_key={os.getenv('LANGTRACE_API_KEY')}"
|
||||
)
|
||||
for callback in _in_memory_loggers:
|
||||
if (
|
||||
isinstance(callback, OpenTelemetry)
|
||||
|
|
@ -4981,16 +4991,22 @@ class StandardLoggingPayloadSetup:
|
|||
|
||||
additional_logging_headers: StandardLoggingAdditionalHeaders = {}
|
||||
|
||||
# Populate well-known typed fields with int/str coercion where needed
|
||||
typed_keys: dict = {}
|
||||
for key in StandardLoggingAdditionalHeaders.__annotations__.keys():
|
||||
_key = key.lower()
|
||||
_key = _key.replace("_", "-")
|
||||
_key = key.lower().replace("_", "-")
|
||||
typed_keys[_key] = key
|
||||
if _key in additiona_headers:
|
||||
try:
|
||||
additional_logging_headers[key] = int(additiona_headers[_key]) # type: ignore
|
||||
except (ValueError, TypeError):
|
||||
verbose_logger.debug(
|
||||
f"Could not convert {additiona_headers[_key]} to int for key {key}."
|
||||
)
|
||||
additional_logging_headers[key] = additiona_headers[_key] # type: ignore
|
||||
|
||||
# Preserve all remaining headers verbatim (e.g. llm_provider-x-request-id)
|
||||
for k, v in additiona_headers.items():
|
||||
if k.lower() not in typed_keys:
|
||||
additional_logging_headers[k] = v # type: ignore
|
||||
|
||||
return additional_logging_headers
|
||||
|
||||
@staticmethod
|
||||
|
|
@ -5012,10 +5028,10 @@ class StandardLoggingPayloadSetup:
|
|||
for key in StandardLoggingHiddenParams.__annotations__.keys():
|
||||
if key in hidden_params:
|
||||
if key == "additional_headers":
|
||||
clean_hidden_params[
|
||||
"additional_headers"
|
||||
] = StandardLoggingPayloadSetup.get_additional_headers(
|
||||
hidden_params[key]
|
||||
clean_hidden_params["additional_headers"] = (
|
||||
StandardLoggingPayloadSetup.get_additional_headers(
|
||||
hidden_params[key]
|
||||
)
|
||||
)
|
||||
else:
|
||||
clean_hidden_params[key] = hidden_params[key] # type: ignore
|
||||
|
|
@ -5656,9 +5672,9 @@ def scrub_sensitive_keys_in_metadata(litellm_params: Optional[dict]):
|
|||
):
|
||||
for k, v in metadata["user_api_key_metadata"].items():
|
||||
if k == "logging": # prevent logging user logging keys
|
||||
cleaned_user_api_key_metadata[
|
||||
k
|
||||
] = "scrubbed_by_litellm_for_sensitive_keys"
|
||||
cleaned_user_api_key_metadata[k] = (
|
||||
"scrubbed_by_litellm_for_sensitive_keys"
|
||||
)
|
||||
else:
|
||||
cleaned_user_api_key_metadata[k] = v
|
||||
|
||||
|
|
|
|||
|
|
@ -11,6 +11,10 @@ from openai.types.completion_create_params import (
|
|||
CompletionCreateParamsStreaming as TextCompletionCreateParamsStreaming,
|
||||
)
|
||||
from openai.types.embedding_create_params import EmbeddingCreateParams
|
||||
from openai.types.responses.response_create_params import (
|
||||
ResponseCreateParamsNonStreaming,
|
||||
ResponseCreateParamsStreaming,
|
||||
)
|
||||
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.types.rerank import RerankRequest
|
||||
|
|
@ -65,6 +69,9 @@ class ModelParamHelper:
|
|||
ModelParamHelper._get_litellm_supported_transcription_kwargs()
|
||||
)
|
||||
rerank_kwargs = ModelParamHelper._get_litellm_supported_rerank_kwargs()
|
||||
responses_api_kwargs = (
|
||||
ModelParamHelper._get_litellm_supported_responses_api_kwargs()
|
||||
)
|
||||
exclude_kwargs = ModelParamHelper._get_exclude_kwargs()
|
||||
|
||||
combined_kwargs = chat_completion_kwargs.union(
|
||||
|
|
@ -72,6 +79,7 @@ class ModelParamHelper:
|
|||
embedding_kwargs,
|
||||
transcription_kwargs,
|
||||
rerank_kwargs,
|
||||
responses_api_kwargs,
|
||||
)
|
||||
combined_kwargs = combined_kwargs.difference(exclude_kwargs)
|
||||
return combined_kwargs
|
||||
|
|
@ -93,9 +101,9 @@ class ModelParamHelper:
|
|||
streaming_params: Set[str] = set(
|
||||
getattr(CompletionCreateParamsStreaming, "__annotations__", {}).keys()
|
||||
)
|
||||
litellm_provider_specific_params: Set[
|
||||
str
|
||||
] = ModelParamHelper.get_litellm_provider_specific_params_for_chat_params()
|
||||
litellm_provider_specific_params: Set[str] = (
|
||||
ModelParamHelper.get_litellm_provider_specific_params_for_chat_params()
|
||||
)
|
||||
all_chat_completion_kwargs: Set[str] = non_streaming_params.union(
|
||||
streaming_params
|
||||
).union(litellm_provider_specific_params)
|
||||
|
|
@ -167,6 +175,21 @@ class ModelParamHelper:
|
|||
verbose_logger.debug("Error getting transcription kwargs %s", str(e))
|
||||
return set()
|
||||
|
||||
@staticmethod
|
||||
def _get_litellm_supported_responses_api_kwargs() -> Set[str]:
|
||||
"""
|
||||
Get the litellm supported responses API kwargs
|
||||
|
||||
This follows the OpenAI API Spec
|
||||
"""
|
||||
non_streaming_params: Set[str] = set(
|
||||
getattr(ResponseCreateParamsNonStreaming, "__annotations__", {}).keys()
|
||||
)
|
||||
streaming_params: Set[str] = set(
|
||||
getattr(ResponseCreateParamsStreaming, "__annotations__", {}).keys()
|
||||
)
|
||||
return non_streaming_params.union(streaming_params)
|
||||
|
||||
@staticmethod
|
||||
def _get_exclude_kwargs() -> Set[str]:
|
||||
"""
|
||||
|
|
|
|||
|
|
@ -5144,26 +5144,44 @@ def _bedrock_tools_pt(tools: List) -> List[BedrockToolBlock]:
|
|||
}
|
||||
]
|
||||
"""
|
||||
from litellm.llms.bedrock.common_utils import (
|
||||
normalize_json_schema_custom_types_to_object,
|
||||
)
|
||||
from litellm.litellm_core_utils.prompt_templates.common_utils import unpack_defs
|
||||
|
||||
_valid_json_schema_root_types = frozenset(
|
||||
("array", "boolean", "integer", "null", "number", "object", "string")
|
||||
)
|
||||
tool_block_list: List[BedrockToolBlock] = []
|
||||
for tool in tools:
|
||||
for tool_idx, tool in enumerate(tools):
|
||||
# Check if tool is already a BedrockToolBlock (e.g., systemTool for Nova grounding)
|
||||
if _is_bedrock_tool_block(tool):
|
||||
# Already a BedrockToolBlock, pass it through
|
||||
tool_block_list.append(tool) # type: ignore
|
||||
continue
|
||||
|
||||
# Handle regular OpenAI-style function tools
|
||||
parameters = tool.get("function", {}).get(
|
||||
"parameters", {"type": "object", "properties": {}}
|
||||
)
|
||||
name = tool.get("function", {}).get("name", "")
|
||||
# OpenAI function tools, or Anthropic Messages / Claude Code ({name, input_schema, type, ...})
|
||||
if isinstance(tool, dict) and "input_schema" in tool and "function" not in tool:
|
||||
parameters = copy.deepcopy(
|
||||
tool.get("input_schema") or {"type": "object", "properties": {}}
|
||||
)
|
||||
raw_name = tool.get("name", "") or ""
|
||||
_tool_description = tool.get("description", None)
|
||||
else:
|
||||
parameters = copy.deepcopy(
|
||||
tool.get("function", {}).get(
|
||||
"parameters", {"type": "object", "properties": {}}
|
||||
)
|
||||
)
|
||||
raw_name = tool.get("function", {}).get("name", "") or ""
|
||||
_tool_description = tool.get("function", {}).get("description", None)
|
||||
|
||||
if not (raw_name and str(raw_name).strip()):
|
||||
raw_name = f"litellm_unnamed_tool_{tool_idx}"
|
||||
|
||||
# related issue: https://github.com/BerriAI/litellm/issues/5007
|
||||
# Bedrock tool names must satisfy regular expression pattern: [a-zA-Z][a-zA-Z0-9_]* ensure this is true
|
||||
name = make_valid_bedrock_tool_name(input_tool_name=name)
|
||||
_tool_description = tool.get("function", {}).get("description", None)
|
||||
name = make_valid_bedrock_tool_name(input_tool_name=raw_name)
|
||||
if _tool_description: # bedrock doesn't accept empty "" or None descriptions
|
||||
description = _tool_description
|
||||
else:
|
||||
|
|
@ -5176,9 +5194,12 @@ def _bedrock_tools_pt(tools: List) -> List[BedrockToolBlock]:
|
|||
# with circular references (see issue #19098). unpack_defs handles nested
|
||||
# refs recursively and correctly detects/skips circular references.
|
||||
unpack_defs(parameters, defs_copy)
|
||||
normalize_json_schema_custom_types_to_object(parameters)
|
||||
if parameters.get("type") not in _valid_json_schema_root_types:
|
||||
parameters["type"] = "object"
|
||||
tool_input_schema = BedrockToolInputSchemaBlock(
|
||||
json=BedrockToolJsonSchemaBlock(
|
||||
type=parameters.get("type", ""),
|
||||
type=parameters["type"],
|
||||
properties=parameters.get("properties", {}),
|
||||
required=parameters.get("required", []),
|
||||
)
|
||||
|
|
|
|||
|
|
@ -67,6 +67,7 @@ from litellm.types.utils import (
|
|||
from litellm.utils import (
|
||||
ModelResponse,
|
||||
Usage,
|
||||
_supports_factory,
|
||||
add_dummy_tool,
|
||||
any_assistant_message_has_thinking_blocks,
|
||||
get_max_tokens,
|
||||
|
|
@ -189,6 +190,30 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
v in model_lower for v in ("opus-4-6", "opus_4_6", "opus-4.6", "opus_4.6")
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def _is_opus_4_7_model(model: str) -> bool:
|
||||
"""Check if the model is specifically Claude Opus 4.7."""
|
||||
model_lower = model.lower()
|
||||
return any(
|
||||
v in model_lower for v in ("opus-4-7", "opus_4_7", "opus-4.7", "opus_4.7")
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def _supports_effort_level(model: str, level: str) -> bool:
|
||||
"""Check ``supports_{level}_reasoning_effort`` in the model map.
|
||||
|
||||
Mirrors the pattern used in ``openai/chat/gpt_5_transformation.py`` so
|
||||
that adding support for a new effort level is a pure model-map change.
|
||||
"""
|
||||
try:
|
||||
return _supports_factory(
|
||||
model=model,
|
||||
custom_llm_provider="anthropic",
|
||||
key=f"supports_{level}_reasoning_effort",
|
||||
)
|
||||
except Exception:
|
||||
return False
|
||||
|
||||
def get_supported_openai_params(self, model: str):
|
||||
params = [
|
||||
"stream",
|
||||
|
|
@ -212,6 +237,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
if (
|
||||
"claude-3-7-sonnet" in model
|
||||
or AnthropicConfig._is_claude_4_6_model(model)
|
||||
or AnthropicConfig._is_claude_4_7_model(model)
|
||||
or supports_reasoning(
|
||||
model=model,
|
||||
custom_llm_provider=self.custom_llm_provider,
|
||||
|
|
@ -771,7 +797,9 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
) -> Optional[AnthropicThinkingParam]:
|
||||
if reasoning_effort is None or reasoning_effort == "none":
|
||||
return None
|
||||
if AnthropicConfig._is_claude_4_6_model(model):
|
||||
if AnthropicConfig._is_claude_4_6_model(
|
||||
model
|
||||
) or AnthropicConfig._is_claude_4_7_model(model):
|
||||
return AnthropicThinkingParam(
|
||||
type="adaptive",
|
||||
)
|
||||
|
|
@ -1020,6 +1048,8 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
"opus-4-5",
|
||||
"opus-4.6",
|
||||
"opus-4-6",
|
||||
"opus-4.7",
|
||||
"opus-4-7",
|
||||
"sonnet-4.6",
|
||||
"sonnet-4-6",
|
||||
"sonnet_4.6",
|
||||
|
|
@ -1061,14 +1091,17 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
optional_params["thinking"] = AnthropicConfig._map_reasoning_effort(
|
||||
reasoning_effort=value, model=model
|
||||
)
|
||||
# For Claude 4.6 models, effort is controlled via output_config,
|
||||
# For Claude 4.6+ models, effort is controlled via output_config,
|
||||
# not thinking budget_tokens. Map reasoning_effort to output_config.
|
||||
if AnthropicConfig._is_claude_4_6_model(model):
|
||||
if AnthropicConfig._is_claude_4_6_model(
|
||||
model
|
||||
) or AnthropicConfig._is_claude_4_7_model(model):
|
||||
effort_map = {
|
||||
"low": "low",
|
||||
"minimal": "low",
|
||||
"medium": "medium",
|
||||
"high": "high",
|
||||
"xhigh": "xhigh",
|
||||
"max": "max",
|
||||
}
|
||||
mapped_effort = effort_map.get(value, value)
|
||||
|
|
@ -1495,13 +1528,24 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
if not output_config or not isinstance(output_config, dict):
|
||||
return
|
||||
effort = output_config.get("effort")
|
||||
if effort and effort not in ["high", "medium", "low", "max"]:
|
||||
valid_efforts = ["high", "medium", "low", "xhigh", "max"]
|
||||
if effort and effort not in valid_efforts:
|
||||
raise ValueError(
|
||||
f"Invalid effort value: {effort}. Must be one of: 'high', 'medium', 'low', 'max'"
|
||||
f"Invalid effort value: {effort}. Must be one of: "
|
||||
f"'high', 'medium', 'low', 'xhigh', 'max'"
|
||||
)
|
||||
# ``max`` is Claude Opus 4.6 only (not Sonnet 4.6, not Opus 4.5/4.7).
|
||||
# Keep this hardcoded so the error message is specific and stable.
|
||||
if effort == "max" and not self._is_opus_4_6_model(model):
|
||||
raise ValueError(
|
||||
f"effort='max' is only supported by Claude Opus 4.6. Got model: {model}"
|
||||
f"effort='max' is only supported by Claude Opus 4.6. "
|
||||
f"Got model: {model}"
|
||||
)
|
||||
# ``xhigh`` is data-driven via ``supports_xhigh_reasoning_effort`` so
|
||||
# enabling it for a new model is a pure model-map change.
|
||||
if effort == "xhigh" and not self._supports_effort_level(model, "xhigh"):
|
||||
raise ValueError(
|
||||
f"effort='xhigh' is not supported by this model. Got model: {model}"
|
||||
)
|
||||
data["output_config"] = output_config
|
||||
|
||||
|
|
@ -1702,10 +1746,12 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
),
|
||||
)
|
||||
|
||||
raw_input_tokens = usage_object.get("input_tokens", 0) or 0
|
||||
prompt_tokens_details = PromptTokensDetailsWrapper(
|
||||
cached_tokens=cache_read_input_tokens,
|
||||
cache_creation_tokens=cache_creation_input_tokens,
|
||||
cache_creation_token_details=cache_creation_token_details,
|
||||
text_tokens=raw_input_tokens,
|
||||
)
|
||||
# Always populate completion_token_details, not just when there's reasoning_content
|
||||
reasoning_tokens = (
|
||||
|
|
|
|||
|
|
@ -2,6 +2,7 @@
|
|||
This file contains common utils for anthropic calls.
|
||||
"""
|
||||
|
||||
import copy
|
||||
from typing import Any, Dict, List, Optional, Union
|
||||
|
||||
import httpx
|
||||
|
|
@ -256,6 +257,27 @@ class AnthropicModelInfo(BaseLLMModelInfo):
|
|||
)
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def _is_claude_4_7_model(model: str) -> bool:
|
||||
"""Check if the model is a Claude 4.7 model (Opus 4.7)."""
|
||||
model_lower = model.lower()
|
||||
return any(
|
||||
v in model_lower
|
||||
for v in (
|
||||
"opus-4-7",
|
||||
"opus_4_7",
|
||||
"opus-4.7",
|
||||
"opus_4.7",
|
||||
)
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def _is_adaptive_thinking_model(model: str) -> bool:
|
||||
"""Claude 4.6+ models use adaptive thinking with output_config effort."""
|
||||
return AnthropicModelInfo._is_claude_4_6_model(
|
||||
model
|
||||
) or AnthropicModelInfo._is_claude_4_7_model(model)
|
||||
|
||||
def is_effort_used(
|
||||
self, optional_params: Optional[dict], model: Optional[str] = None
|
||||
) -> bool:
|
||||
|
|
@ -263,14 +285,14 @@ class AnthropicModelInfo(BaseLLMModelInfo):
|
|||
Check if effort parameter is being used and requires a beta header.
|
||||
|
||||
Returns True if effort-related parameters are present and
|
||||
the model requires the effort beta header. Claude 4.6 models
|
||||
the model requires the effort beta header. Claude 4.6+ models
|
||||
use output_config as a stable API feature — no beta header needed.
|
||||
"""
|
||||
if not optional_params:
|
||||
return False
|
||||
|
||||
# Claude 4.6 models use output_config as a stable API feature — no beta header needed
|
||||
if model and self._is_claude_4_6_model(model):
|
||||
# Claude 4.6+ models use output_config as a stable API feature — no beta header needed
|
||||
if model and self._is_adaptive_thinking_model(model):
|
||||
return False
|
||||
|
||||
# Check if reasoning_effort is provided for Claude Opus 4.5
|
||||
|
|
@ -736,6 +758,69 @@ def strip_advisor_blocks_from_messages(
|
|||
return messages
|
||||
|
||||
|
||||
def is_anthropic_invalid_thinking_signature_error(error_text: str) -> bool:
|
||||
"""
|
||||
Detect Anthropic 400 when encrypted thinking signatures in history do not match
|
||||
the current deployment (e.g. user rotated API key or switched model endpoint).
|
||||
|
||||
Example API message:
|
||||
messages.N.content.M: Invalid `signature` in `thinking` block
|
||||
"""
|
||||
if not error_text:
|
||||
return False
|
||||
lower = error_text.lower()
|
||||
return (
|
||||
"invalid" in lower
|
||||
and "signature" in lower
|
||||
and "thinking" in lower
|
||||
and "block" in lower
|
||||
)
|
||||
|
||||
|
||||
def strip_thinking_blocks_from_anthropic_messages(messages: List[Any]) -> List[Any]:
|
||||
"""
|
||||
Return a new message list with thinking / redacted_thinking content blocks removed
|
||||
from each message. Used to recover from invalid thinking signatures on retry.
|
||||
|
||||
Messages whose content is a list and becomes empty after stripping are omitted,
|
||||
since Anthropic rejects empty content arrays.
|
||||
"""
|
||||
out: List[Any] = []
|
||||
for m in messages:
|
||||
if not isinstance(m, dict):
|
||||
out.append(m)
|
||||
continue
|
||||
mm = copy.deepcopy(m)
|
||||
content = mm.get("content")
|
||||
if isinstance(content, list):
|
||||
filtered = [
|
||||
b
|
||||
for b in content
|
||||
if not (
|
||||
isinstance(b, dict)
|
||||
and b.get("type") in ("thinking", "redacted_thinking")
|
||||
)
|
||||
]
|
||||
if not filtered:
|
||||
continue
|
||||
mm["content"] = filtered
|
||||
out.append(mm)
|
||||
return out
|
||||
|
||||
|
||||
def strip_thinking_blocks_from_anthropic_messages_request_dict(
|
||||
data: Dict[str, Any],
|
||||
) -> None:
|
||||
"""
|
||||
Mutate an Anthropic Messages-style request dict: strip thinking blocks from
|
||||
``messages`` and remove the top-level ``thinking`` extended-thinking param.
|
||||
"""
|
||||
msgs = data.get("messages")
|
||||
if isinstance(msgs, list):
|
||||
data["messages"] = strip_thinking_blocks_from_anthropic_messages(msgs)
|
||||
data.pop("thinking", None)
|
||||
|
||||
|
||||
def process_anthropic_headers(headers: Union[httpx.Headers, dict]) -> dict:
|
||||
openai_headers = {}
|
||||
if "anthropic-ratelimit-requests-limit" in headers:
|
||||
|
|
|
|||
|
|
@ -129,14 +129,22 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
|
|||
|
||||
if should_start_new_block and not self.sent_content_block_finish:
|
||||
# Queue the sequence: content_block_stop -> content_block_start
|
||||
# The trigger chunk itself is not emitted as a delta since the
|
||||
# content_block_start already carries the relevant information.
|
||||
# For text blocks the trigger chunk is not emitted as a separate
|
||||
# delta because content_block_start carries the information.
|
||||
# For tool_use blocks we must also emit the trigger chunk's delta
|
||||
# when it carries input_json_delta data, because some providers
|
||||
# (e.g. xAI, Gemini) include tool arguments in the same streaming
|
||||
# chunk as the function name/id.
|
||||
|
||||
# 1. Stop current content block
|
||||
self.chunk_queue.append(
|
||||
{
|
||||
"type": "content_block_stop",
|
||||
"index": max(self.current_content_block_index - 1, 0),
|
||||
}
|
||||
)
|
||||
|
||||
# 2. Start new content block
|
||||
self.chunk_queue.append(
|
||||
{
|
||||
"type": "content_block_start",
|
||||
|
|
@ -144,6 +152,17 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
|
|||
"content_block": self.current_content_block_start,
|
||||
}
|
||||
)
|
||||
|
||||
# 3. If the trigger chunk carries tool argument data, queue it
|
||||
# so the input_json_delta is not silently dropped.
|
||||
if (
|
||||
processed_chunk.get("type") == "content_block_delta"
|
||||
and isinstance(processed_chunk.get("delta"), dict)
|
||||
and processed_chunk["delta"].get("type") == "input_json_delta"
|
||||
and processed_chunk["delta"].get("partial_json")
|
||||
):
|
||||
self.chunk_queue.append(processed_chunk)
|
||||
|
||||
self.sent_content_block_finish = False
|
||||
return self.chunk_queue.popleft()
|
||||
|
||||
|
|
@ -282,16 +301,16 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
|
|||
hasattr(chunk.usage, "_cache_creation_input_tokens")
|
||||
and chunk.usage._cache_creation_input_tokens > 0
|
||||
):
|
||||
usage_dict[
|
||||
"cache_creation_input_tokens"
|
||||
] = chunk.usage._cache_creation_input_tokens
|
||||
usage_dict["cache_creation_input_tokens"] = (
|
||||
chunk.usage._cache_creation_input_tokens
|
||||
)
|
||||
if (
|
||||
hasattr(chunk.usage, "_cache_read_input_tokens")
|
||||
and chunk.usage._cache_read_input_tokens > 0
|
||||
):
|
||||
usage_dict[
|
||||
"cache_read_input_tokens"
|
||||
] = chunk.usage._cache_read_input_tokens
|
||||
usage_dict["cache_read_input_tokens"] = (
|
||||
chunk.usage._cache_read_input_tokens
|
||||
)
|
||||
merged_chunk["usage"] = usage_dict
|
||||
|
||||
# Queue the merged chunk and reset
|
||||
|
|
@ -305,8 +324,12 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
|
|||
if not self.queued_usage_chunk:
|
||||
if should_start_new_block and not self.sent_content_block_finish:
|
||||
# Queue the sequence: content_block_stop -> content_block_start
|
||||
# The trigger chunk itself is not emitted as a delta since the
|
||||
# content_block_start already carries the relevant information.
|
||||
# For text blocks the trigger chunk is not emitted as a separate
|
||||
# delta because content_block_start carries the information.
|
||||
# For tool_use blocks we must also emit the trigger chunk's delta
|
||||
# when it carries input_json_delta data, because some providers
|
||||
# (e.g. xAI, Gemini) include tool arguments in the same streaming
|
||||
# chunk as the function name/id.
|
||||
|
||||
# 1. Stop current content block
|
||||
self.chunk_queue.append(
|
||||
|
|
@ -325,6 +348,17 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
|
|||
}
|
||||
)
|
||||
|
||||
# 3. If the trigger chunk carries tool argument data, queue it
|
||||
# so the input_json_delta is not silently dropped.
|
||||
if (
|
||||
processed_chunk.get("type") == "content_block_delta"
|
||||
and isinstance(processed_chunk.get("delta"), dict)
|
||||
and processed_chunk["delta"].get("type")
|
||||
== "input_json_delta"
|
||||
and processed_chunk["delta"].get("partial_json")
|
||||
):
|
||||
self.chunk_queue.append(processed_chunk)
|
||||
|
||||
# Reset state for new block
|
||||
self.sent_content_block_finish = False
|
||||
|
||||
|
|
|
|||
|
|
@ -796,7 +796,7 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
tool_name_mapping: Dict[str, str] = {}
|
||||
mapped_tool_params = ["name", "input_schema", "description", "cache_control"]
|
||||
|
||||
for tool in tools:
|
||||
for idx, tool in enumerate(tools):
|
||||
# Check if this is an Anthropic-native tool that should be kept as-is
|
||||
tool_type = tool.get("type", "")
|
||||
if any(tool_type.startswith(t.value) for t in ANTHROPIC_HOSTED_TOOLS):
|
||||
|
|
@ -804,7 +804,13 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
new_tools.append(tool) # type: ignore[arg-type]
|
||||
continue
|
||||
|
||||
original_name = tool["name"]
|
||||
raw_name = tool.get("name")
|
||||
if raw_name is None or (
|
||||
isinstance(raw_name, str) and not str(raw_name).strip()
|
||||
):
|
||||
original_name = f"litellm_unnamed_tool_{idx}"
|
||||
else:
|
||||
original_name = str(raw_name)
|
||||
truncated_name = truncate_tool_name(original_name)
|
||||
|
||||
# Store mapping if name was truncated
|
||||
|
|
|
|||
|
|
@ -27,6 +27,7 @@ class BaseAnthropicMessagesStreamingIterator:
|
|||
self.litellm_logging_obj = litellm_logging_obj
|
||||
self.request_body = request_body
|
||||
self.start_time = datetime.now()
|
||||
self.completion_start_time: datetime | None = None
|
||||
|
||||
async def _handle_streaming_logging(self, collected_chunks: List[bytes]):
|
||||
"""Handle the logging after all chunks have been collected."""
|
||||
|
|
@ -35,6 +36,15 @@ class BaseAnthropicMessagesStreamingIterator:
|
|||
)
|
||||
|
||||
end_time = datetime.now()
|
||||
# Set completion_start_time so TTFT is calculated from the first
|
||||
# chunk rather than falling back to end_time in async_success_handler.
|
||||
if self.completion_start_time is not None:
|
||||
self.litellm_logging_obj.completion_start_time = (
|
||||
self.completion_start_time
|
||||
)
|
||||
self.litellm_logging_obj.model_call_details[
|
||||
"completion_start_time"
|
||||
] = self.completion_start_time
|
||||
asyncio.create_task(
|
||||
PassThroughStreamingHandler._route_streaming_logging_to_handler(
|
||||
litellm_logging_obj=self.litellm_logging_obj,
|
||||
|
|
@ -100,6 +110,8 @@ class BaseAnthropicMessagesStreamingIterator:
|
|||
collected_chunks = []
|
||||
|
||||
async for chunk in completion_stream:
|
||||
if self.completion_start_time is None:
|
||||
self.completion_start_time = datetime.now()
|
||||
encoded_chunk = self._convert_chunk_to_sse_format(chunk)
|
||||
collected_chunks.append(encoded_chunk)
|
||||
yield encoded_chunk
|
||||
|
|
|
|||
|
|
@ -166,6 +166,36 @@ class AnthropicMessagesConfig(BaseAnthropicMessagesConfig):
|
|||
|
||||
return headers, api_base
|
||||
|
||||
@staticmethod
|
||||
def _translate_legacy_thinking_for_adaptive_model(
|
||||
model: str, optional_params: Dict
|
||||
) -> None:
|
||||
"""Translate legacy ``thinking.type=enabled`` to adaptive for 4.6/4.7.
|
||||
Caller-provided ``output_config.effort`` is never overridden.
|
||||
"""
|
||||
if not AnthropicModelInfo._is_adaptive_thinking_model(model):
|
||||
return
|
||||
thinking = optional_params.get("thinking")
|
||||
if not isinstance(thinking, dict) or thinking.get("type") != "enabled":
|
||||
return
|
||||
|
||||
budget = int(thinking.get("budget_tokens") or 0)
|
||||
if budget >= 24000:
|
||||
effort = "xhigh"
|
||||
elif budget >= 10000:
|
||||
effort = "high"
|
||||
elif budget >= 5000:
|
||||
effort = "medium"
|
||||
else:
|
||||
effort = "low"
|
||||
|
||||
optional_params["thinking"] = {"type": "adaptive"}
|
||||
existing_output_config = optional_params.get("output_config")
|
||||
if not isinstance(existing_output_config, dict):
|
||||
existing_output_config = {}
|
||||
existing_output_config.setdefault("effort", effort)
|
||||
optional_params["output_config"] = existing_output_config
|
||||
|
||||
def transform_anthropic_messages_request(
|
||||
self,
|
||||
model: str,
|
||||
|
|
@ -187,6 +217,11 @@ class AnthropicMessagesConfig(BaseAnthropicMessagesConfig):
|
|||
status_code=400,
|
||||
)
|
||||
|
||||
self._translate_legacy_thinking_for_adaptive_model(
|
||||
model=model,
|
||||
optional_params=anthropic_messages_optional_request_params,
|
||||
)
|
||||
|
||||
# Filter out x-anthropic-billing-header from system messages
|
||||
system_param = anthropic_messages_optional_request_params.get("system")
|
||||
if system_param is not None:
|
||||
|
|
|
|||
|
|
@ -1,7 +1,9 @@
|
|||
from typing import TYPE_CHECKING, List, Optional, Tuple
|
||||
|
||||
import httpx
|
||||
from httpx import Response
|
||||
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging
|
||||
from litellm.llms.azure.common_utils import BaseAzureLLM
|
||||
from litellm.llms.base_llm.passthrough.transformation import BasePassthroughConfig
|
||||
from litellm.secret_managers.main import get_secret_str
|
||||
|
|
@ -11,6 +13,8 @@ from litellm.types.router import GenericLiteLLMParams
|
|||
if TYPE_CHECKING:
|
||||
from httpx import URL
|
||||
|
||||
from litellm.types.utils import CostResponseTypes
|
||||
|
||||
|
||||
class AzurePassthroughConfig(BasePassthroughConfig):
|
||||
def is_streaming_request(self, endpoint: str, request_data: dict) -> bool:
|
||||
|
|
@ -83,3 +87,36 @@ class AzurePassthroughConfig(BasePassthroughConfig):
|
|||
self, api_key: Optional[str] = None, api_base: Optional[str] = None
|
||||
) -> List[str]:
|
||||
return super().get_models(api_key, api_base)
|
||||
|
||||
def logging_non_streaming_response(
|
||||
self,
|
||||
model: str,
|
||||
custom_llm_provider: str,
|
||||
httpx_response: Response,
|
||||
request_data: dict,
|
||||
logging_obj: Logging,
|
||||
endpoint: str,
|
||||
) -> Optional["CostResponseTypes"]:
|
||||
from litellm import encoding
|
||||
from litellm.llms.openai.chat.gpt_transformation import OpenAIGPTConfig
|
||||
from litellm.types.utils import ModelResponse
|
||||
|
||||
if "chat/completions" not in endpoint:
|
||||
return None
|
||||
|
||||
openai_chat_config = OpenAIGPTConfig()
|
||||
|
||||
litellm_model_response: ModelResponse = openai_chat_config.transform_response(
|
||||
model=model,
|
||||
messages=[{"role": "user", "content": "no-message-pass-through-endpoint"}],
|
||||
raw_response=httpx_response,
|
||||
model_response=ModelResponse(),
|
||||
logging_obj=logging_obj,
|
||||
optional_params={},
|
||||
litellm_params={},
|
||||
api_key="",
|
||||
request_data=request_data,
|
||||
encoding=encoding,
|
||||
)
|
||||
|
||||
return litellm_model_response
|
||||
|
|
|
|||
|
|
@ -6,7 +6,7 @@ This requires websockets, and is currently only supported on LiteLLM Proxy.
|
|||
|
||||
from typing import Any, Optional, cast
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm._logging import _redact_string, verbose_proxy_logger
|
||||
from litellm.constants import REALTIME_WEBSOCKET_MAX_MESSAGE_SIZE_BYTES
|
||||
|
||||
from ....litellm_core_utils.litellm_logging import Logging as LiteLLMLogging
|
||||
|
|
@ -118,7 +118,7 @@ class AzureOpenAIRealtime(AzureChatCompletion):
|
|||
await realtime_streaming.bidirectional_forward()
|
||||
|
||||
except websockets.exceptions.InvalidStatusCode as e: # type: ignore
|
||||
await websocket.close(code=e.status_code, reason=str(e))
|
||||
await websocket.close(code=e.status_code, reason=_redact_string(str(e)))
|
||||
except Exception:
|
||||
verbose_proxy_logger.exception(
|
||||
"Error in AzureOpenAIRealtime.async_realtime"
|
||||
|
|
|
|||
|
|
@ -120,3 +120,46 @@ class BaseAnthropicMessagesConfig(ABC):
|
|||
return BaseLLMException(
|
||||
message=error_message, status_code=status_code, headers=headers
|
||||
)
|
||||
|
||||
@property
|
||||
def max_retry_on_anthropic_messages_http_error(self) -> int:
|
||||
"""
|
||||
Max HTTP attempts for /v1/messages when the handler may mutate the body and
|
||||
retry (e.g. strip invalid encrypted thinking signatures after a deployment or
|
||||
credential change).
|
||||
"""
|
||||
return 2
|
||||
|
||||
def should_retry_anthropic_messages_on_http_error(
|
||||
self, e: httpx.HTTPStatusError, litellm_params: dict
|
||||
) -> bool:
|
||||
"""
|
||||
When True, async_anthropic_messages_handler will transform the request body
|
||||
and issue one more attempt (bounded by max_retry_on_anthropic_messages_http_error).
|
||||
"""
|
||||
from litellm.llms.anthropic.common_utils import (
|
||||
is_anthropic_invalid_thinking_signature_error,
|
||||
)
|
||||
|
||||
return (
|
||||
e.response.status_code == 400
|
||||
and is_anthropic_invalid_thinking_signature_error(e.response.text)
|
||||
)
|
||||
|
||||
def transform_anthropic_messages_request_on_http_error(
|
||||
self, e: httpx.HTTPStatusError, request_data: dict
|
||||
) -> dict:
|
||||
"""
|
||||
Mutates request_data in place when retrying after a recoverable HTTP error.
|
||||
"""
|
||||
from litellm.llms.anthropic.common_utils import (
|
||||
is_anthropic_invalid_thinking_signature_error,
|
||||
strip_thinking_blocks_from_anthropic_messages_request_dict,
|
||||
)
|
||||
|
||||
if (
|
||||
e.response.status_code == 400
|
||||
and is_anthropic_invalid_thinking_signature_error(e.response.text)
|
||||
):
|
||||
strip_thinking_blocks_from_anthropic_messages_request_dict(request_data)
|
||||
return request_data
|
||||
|
|
|
|||
|
|
@ -1003,7 +1003,7 @@ class AmazonConverseConfig(BaseConfig):
|
|||
description=description,
|
||||
)
|
||||
optional_params["outputConfig"] = output_config
|
||||
else:
|
||||
elif json_schema is not None:
|
||||
# Fallback: translate to a synthetic tool call
|
||||
# https://docs.anthropic.com/en/docs/build-with-claude/tool-use#json-mode
|
||||
_tool = self._create_json_tool_call_for_response_format(
|
||||
|
|
@ -1025,6 +1025,12 @@ class AmazonConverseConfig(BaseConfig):
|
|||
)
|
||||
if non_default_params.get("stream", False) is True:
|
||||
optional_params["fake_stream"] = True
|
||||
# else: response_format=json_object with no schema.
|
||||
# Don't inject the synthetic json_tool_call tool here. When no
|
||||
# schema is given, _create_json_tool_call_for_response_format
|
||||
# produces an empty schema (properties: {}), and the model
|
||||
# returns {} instead of the requested JSON. The model already
|
||||
# returns JSON when the prompt asks for it.
|
||||
|
||||
optional_params["json_mode"] = True
|
||||
return optional_params
|
||||
|
|
@ -1298,12 +1304,16 @@ class AmazonConverseConfig(BaseConfig):
|
|||
# Add computer use tools and anthropic_beta if needed (only when computer use tools are present)
|
||||
if computer_use_tools:
|
||||
# Determine the correct computer-use beta header based on model
|
||||
# "computer-use-2025-11-24" for Claude Opus 4.6, Claude Opus 4.5
|
||||
# "computer-use-2025-11-24" for Claude Opus 4.7, Opus 4.6, and Opus 4.5
|
||||
# "computer-use-2025-01-24" for Claude Sonnet 4.5, Haiku 4.5, Opus 4.1, Sonnet 4, Opus 4, and Sonnet 3.7
|
||||
# "computer-use-2024-10-22" for older models
|
||||
model_lower = model.lower()
|
||||
if (
|
||||
"opus-4.6" in model_lower
|
||||
"opus-4.7" in model_lower
|
||||
or "opus_4.7" in model_lower
|
||||
or "opus-4-7" in model_lower
|
||||
or "opus_4_7" in model_lower
|
||||
or "opus-4.6" in model_lower
|
||||
or "opus_4.6" in model_lower
|
||||
or "opus-4-6" in model_lower
|
||||
or "opus_4_6" in model_lower
|
||||
|
|
@ -1651,6 +1661,7 @@ class AmazonConverseConfig(BaseConfig):
|
|||
cache_creation_input_tokens: int = 0
|
||||
cache_read_input_tokens: int = 0
|
||||
|
||||
raw_input_tokens = input_tokens # capture before inflation
|
||||
if "cacheReadInputTokens" in usage:
|
||||
cache_read_input_tokens = usage["cacheReadInputTokens"]
|
||||
input_tokens += cache_read_input_tokens
|
||||
|
|
@ -1659,7 +1670,9 @@ class AmazonConverseConfig(BaseConfig):
|
|||
input_tokens += cache_creation_input_tokens
|
||||
|
||||
prompt_tokens_details = PromptTokensDetailsWrapper(
|
||||
cached_tokens=cache_read_input_tokens
|
||||
cached_tokens=cache_read_input_tokens,
|
||||
cache_creation_tokens=cache_creation_input_tokens,
|
||||
text_tokens=raw_input_tokens,
|
||||
)
|
||||
reasoning_tokens = (
|
||||
token_counter(text=reasoning_content, count_response_tokens=True)
|
||||
|
|
@ -2027,6 +2040,12 @@ class AmazonConverseConfig(BaseConfig):
|
|||
_message = Message(**chat_completion_message)
|
||||
initial_finish_reason = map_finish_reason(completion_response["stopReason"])
|
||||
|
||||
# When json_mode filtered out all synthetic tool calls the response
|
||||
# is plain content, not a pending tool invocation. Fix finish_reason
|
||||
# so callers (e.g. OpenAI SDK) don't misinterpret it.
|
||||
if json_mode and not filtered_tools and tools:
|
||||
initial_finish_reason = "stop"
|
||||
|
||||
(
|
||||
returned_message,
|
||||
returned_finish_reason,
|
||||
|
|
|
|||
|
|
@ -16,6 +16,7 @@ from litellm.llms.bedrock.chat.invoke_transformations.base_invoke_transformation
|
|||
)
|
||||
from litellm.llms.bedrock.common_utils import (
|
||||
get_anthropic_beta_from_headers,
|
||||
normalize_tool_input_schema_types_for_bedrock_invoke,
|
||||
remove_custom_field_from_tools,
|
||||
)
|
||||
from litellm.types.llms.anthropic import ANTHROPIC_TOOL_SEARCH_BETA_HEADER
|
||||
|
|
@ -174,6 +175,7 @@ class AmazonAnthropicClaudeConfig(AmazonInvokeConfig, AnthropicConfig):
|
|||
|
||||
# Remove `custom` field from tools (Bedrock doesn't support it)
|
||||
remove_custom_field_from_tools(anthropic_request)
|
||||
normalize_tool_input_schema_types_for_bedrock_invoke(anthropic_request)
|
||||
return anthropic_request
|
||||
|
||||
def _compute_bedrock_invoke_beta_headers(
|
||||
|
|
|
|||
|
|
@ -6,7 +6,7 @@ Common utilities used across bedrock chat/embedding/image generation
|
|||
|
||||
import json
|
||||
import os
|
||||
from typing import TYPE_CHECKING, Dict, List, Literal, Optional, Union
|
||||
from typing import TYPE_CHECKING, Any, Dict, List, Literal, Optional, Union
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from litellm.types.llms.bedrock import BedrockCreateBatchRequest
|
||||
|
|
@ -70,6 +70,88 @@ def remove_custom_field_from_tools(request_body: dict) -> None:
|
|||
tool.pop("custom", None)
|
||||
|
||||
|
||||
def normalize_json_schema_custom_types_to_object(schema: dict) -> None:
|
||||
"""
|
||||
In-place: replace JSON Schema ``type: \"custom\"`` with ``\"object\"`` (iterative walk).
|
||||
|
||||
Anthropic / Claude Code use ``custom`` for tool schemas; Bedrock Invoke and
|
||||
Bedrock Converse only accept standard JSON Schema type strings.
|
||||
|
||||
Uses an explicit stack (not recursion) to satisfy recursive-function guards in CI.
|
||||
"""
|
||||
stack: List[Any] = [schema]
|
||||
seen: set[int] = set()
|
||||
while stack:
|
||||
node = stack.pop()
|
||||
if not isinstance(node, dict):
|
||||
continue
|
||||
node_id = id(node)
|
||||
if node_id in seen:
|
||||
continue
|
||||
seen.add(node_id)
|
||||
if node.get("type") == "custom":
|
||||
node["type"] = "object"
|
||||
items = node.get("items")
|
||||
if isinstance(items, dict):
|
||||
stack.append(items)
|
||||
addl = node.get("additionalProperties")
|
||||
if isinstance(addl, dict):
|
||||
stack.append(addl)
|
||||
props = node.get("properties")
|
||||
if isinstance(props, dict):
|
||||
for sub in props.values():
|
||||
if isinstance(sub, dict):
|
||||
stack.append(sub)
|
||||
for combiner in ("allOf", "anyOf", "oneOf"):
|
||||
arr = node.get(combiner)
|
||||
if isinstance(arr, list):
|
||||
for sub in arr:
|
||||
if isinstance(sub, dict):
|
||||
stack.append(sub)
|
||||
|
||||
|
||||
def normalize_tool_input_schema_types_for_bedrock_invoke(request_body: dict) -> None:
|
||||
"""
|
||||
Bedrock Invoke (Anthropic Messages) validates ``input_schema`` as JSON Schema.
|
||||
Anthropic's API allows ``type: \"custom\"`` for Claude Code custom tools; Bedrock
|
||||
rejects it with: ``tools.0.custom.input_schema.type: Input should be 'object'``.
|
||||
|
||||
Normalizes ``type: \"custom\"`` to ``\"object\"`` throughout each tool's
|
||||
``input_schema`` (recursive for nested properties, items, combinators).
|
||||
|
||||
Args:
|
||||
request_body: Request dictionary to modify in-place.
|
||||
"""
|
||||
tools = request_body.get("tools")
|
||||
if not tools or not isinstance(tools, list):
|
||||
return
|
||||
for tool in tools:
|
||||
if not isinstance(tool, dict):
|
||||
continue
|
||||
input_schema = tool.get("input_schema")
|
||||
if isinstance(input_schema, dict):
|
||||
normalize_json_schema_custom_types_to_object(input_schema)
|
||||
|
||||
|
||||
def ensure_bedrock_anthropic_messages_tool_names(request_body: dict) -> None:
|
||||
"""
|
||||
Bedrock Invoke (Anthropic Messages) requires each tool to include ``name``.
|
||||
Some clients send only ``input_schema``; Bedrock then errors with
|
||||
``tools.0.custom.name: Field required``.
|
||||
|
||||
In-place: set ``name`` to ``litellm_unnamed_tool_{index}`` when missing or blank.
|
||||
"""
|
||||
tools = request_body.get("tools")
|
||||
if not tools or not isinstance(tools, list):
|
||||
return
|
||||
for i, tool in enumerate(tools):
|
||||
if not isinstance(tool, dict):
|
||||
continue
|
||||
name = tool.get("name")
|
||||
if name is None or (isinstance(name, str) and not name.strip()):
|
||||
tool["name"] = f"litellm_unnamed_tool_{i}"
|
||||
|
||||
|
||||
class AmazonBedrockGlobalConfig:
|
||||
def __init__(self):
|
||||
pass
|
||||
|
|
@ -507,6 +589,10 @@ def is_claude_4_5_on_bedrock(model: str) -> bool:
|
|||
"opus_4.6",
|
||||
"opus-4-6",
|
||||
"opus_4_6",
|
||||
"opus-4.7",
|
||||
"opus_4.7",
|
||||
"opus-4-7",
|
||||
"opus_4_7",
|
||||
]
|
||||
return any(pattern in model_lower for pattern in claude_4_5_patterns)
|
||||
|
||||
|
|
|
|||
|
|
@ -13,6 +13,8 @@ from typing import (
|
|||
import httpx
|
||||
|
||||
from litellm.anthropic_beta_headers_manager import filter_and_transform_beta_headers
|
||||
from litellm.constants import BEDROCK_MIN_THINKING_BUDGET_TOKENS
|
||||
from litellm.litellm_core_utils.litellm_logging import verbose_logger
|
||||
from litellm.llms.anthropic.common_utils import AnthropicModelInfo
|
||||
from litellm.llms.anthropic.experimental_pass_through.messages.transformation import (
|
||||
AnthropicMessagesConfig,
|
||||
|
|
@ -25,8 +27,10 @@ from litellm.llms.bedrock.chat.invoke_transformations.base_invoke_transformation
|
|||
AmazonInvokeConfig,
|
||||
)
|
||||
from litellm.llms.bedrock.common_utils import (
|
||||
ensure_bedrock_anthropic_messages_tool_names,
|
||||
get_anthropic_beta_from_headers,
|
||||
is_claude_4_5_on_bedrock,
|
||||
normalize_tool_input_schema_types_for_bedrock_invoke,
|
||||
remove_custom_field_from_tools,
|
||||
)
|
||||
from litellm.types.llms.anthropic import ANTHROPIC_TOOL_SEARCH_BETA_HEADER
|
||||
|
|
@ -203,10 +207,78 @@ class AmazonAnthropicClaudeMessagesConfig(
|
|||
"opus_4.6",
|
||||
"opus-4-6",
|
||||
"opus_4_6",
|
||||
"opus-4.7",
|
||||
"opus_4.7",
|
||||
"opus-4-7",
|
||||
"opus_4_7",
|
||||
]
|
||||
|
||||
return any(pattern in model_lower for pattern in supported_patterns)
|
||||
|
||||
def _ensure_thinking_for_clear_thinking_context_management(
|
||||
self,
|
||||
anthropic_messages_request: Dict,
|
||||
model: str,
|
||||
) -> bool:
|
||||
"""
|
||||
Bedrock rejects ``clear_thinking_20251015`` context-management edits unless
|
||||
extended thinking is ``enabled`` or ``adaptive``. Claude Code often sends
|
||||
context management without a top-level ``thinking`` field.
|
||||
|
||||
When we detect that edit type on a model that supports extended thinking on
|
||||
Bedrock, inject a minimal ``thinking`` config so the request succeeds.
|
||||
|
||||
Returns:
|
||||
True if ``thinking`` was added or upgraded for this fix (caller may
|
||||
need to add the interleaved-thinking beta header).
|
||||
"""
|
||||
cm = anthropic_messages_request.get("context_management")
|
||||
if not isinstance(cm, dict):
|
||||
return False
|
||||
edits = cm.get("edits")
|
||||
if not isinstance(edits, list):
|
||||
return False
|
||||
needs_thinking = any(
|
||||
isinstance(e, dict) and e.get("type") == "clear_thinking_20251015"
|
||||
for e in edits
|
||||
)
|
||||
if not needs_thinking:
|
||||
return False
|
||||
if not self._supports_extended_thinking_on_bedrock(model):
|
||||
return False
|
||||
|
||||
thinking = anthropic_messages_request.get("thinking")
|
||||
if isinstance(thinking, dict):
|
||||
t = thinking.get("type")
|
||||
if t in ("enabled", "adaptive"):
|
||||
return False
|
||||
# ``disabled`` or unknown — replace with enabled so clear_thinking is valid
|
||||
verbose_logger.debug(
|
||||
"Bedrock clear_thinking_20251015: replacing thinking=%s with minimal enabled thinking",
|
||||
thinking,
|
||||
)
|
||||
|
||||
max_tokens = anthropic_messages_request.get("max_tokens")
|
||||
budget = BEDROCK_MIN_THINKING_BUDGET_TOKENS
|
||||
if isinstance(max_tokens, int) and max_tokens <= budget:
|
||||
verbose_logger.warning(
|
||||
"Bedrock clear_thinking_20251015: max_tokens=%s is not greater than "
|
||||
"minimum thinking budget (%s); cannot inject thinking safely",
|
||||
max_tokens,
|
||||
budget,
|
||||
)
|
||||
return False
|
||||
|
||||
anthropic_messages_request["thinking"] = {
|
||||
"type": "enabled",
|
||||
"budget_tokens": budget,
|
||||
}
|
||||
verbose_logger.debug(
|
||||
"Bedrock clear_thinking_20251015: injected thinking with budget_tokens=%s",
|
||||
budget,
|
||||
)
|
||||
return True
|
||||
|
||||
def _is_claude_opus_4_5(self, model: str) -> bool:
|
||||
"""
|
||||
Check if the model is Claude Opus 4.5.
|
||||
|
|
@ -279,6 +351,10 @@ class AmazonAnthropicClaudeMessagesConfig(
|
|||
"sonnet_4.6",
|
||||
"sonnet-4-6",
|
||||
"sonnet_4_6",
|
||||
# NOTE: Opus 4.7 on Bedrock does not support server-side tool search
|
||||
# as of launch (2026-04-16). Bedrock rejects the tool type with:
|
||||
# "tool type 'tool_search_tool_..._20251119' is not supported for this model".
|
||||
# Re-add the opus-4.7 patterns here once AWS announces support.
|
||||
]
|
||||
|
||||
return any(pattern in model_lower for pattern in supported_patterns)
|
||||
|
|
@ -404,6 +480,13 @@ class AmazonAnthropicClaudeMessagesConfig(
|
|||
if "model" in anthropic_messages_request:
|
||||
anthropic_messages_request.pop("model", None)
|
||||
|
||||
injected_thinking_for_clear_thinking = (
|
||||
self._ensure_thinking_for_clear_thinking_context_management(
|
||||
anthropic_messages_request=anthropic_messages_request,
|
||||
model=model,
|
||||
)
|
||||
)
|
||||
|
||||
# 4. Remove `ttl` field from cache_control in messages (Bedrock doesn't support it for older models)
|
||||
self._remove_ttl_from_cache_control(
|
||||
anthropic_messages_request=anthropic_messages_request, model=model
|
||||
|
|
@ -426,6 +509,8 @@ class AmazonAnthropicClaudeMessagesConfig(
|
|||
# which causes Bedrock to reject the request with "Extra inputs are not permitted"
|
||||
# Ref: https://github.com/BerriAI/litellm/issues/22847
|
||||
remove_custom_field_from_tools(anthropic_messages_request)
|
||||
normalize_tool_input_schema_types_for_bedrock_invoke(anthropic_messages_request)
|
||||
ensure_bedrock_anthropic_messages_tool_names(anthropic_messages_request)
|
||||
|
||||
# 6. AUTO-INJECT beta headers based on features used
|
||||
anthropic_model_info = AnthropicModelInfo()
|
||||
|
|
@ -451,6 +536,9 @@ class AmazonAnthropicClaudeMessagesConfig(
|
|||
)
|
||||
beta_set.update(auto_betas)
|
||||
|
||||
if injected_thinking_for_clear_thinking:
|
||||
beta_set.add("interleaved-thinking-2025-05-14")
|
||||
|
||||
self._get_tool_search_beta_header_for_bedrock(
|
||||
model=model,
|
||||
tool_search_used=tool_search_used,
|
||||
|
|
|
|||
|
|
@ -8,7 +8,7 @@ import asyncio
|
|||
import json
|
||||
from typing import Any, Optional
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm._logging import _redact_string, verbose_proxy_logger
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLogging
|
||||
|
||||
from ..base_aws_llm import BaseAWSLLM
|
||||
|
|
@ -152,7 +152,7 @@ class BedrockRealtime(BaseAWSLLM):
|
|||
f"Error in BedrockRealtime.async_realtime: {e}"
|
||||
)
|
||||
try:
|
||||
await websocket.close(code=1011, reason=f"Internal error: {str(e)}")
|
||||
await websocket.close(code=1011, reason=_redact_string(f"Internal error: {str(e)}"))
|
||||
except Exception:
|
||||
pass
|
||||
raise
|
||||
|
|
|
|||
|
|
@ -30,7 +30,9 @@ from litellm.constants import (
|
|||
AIOHTTP_KEEPALIVE_TIMEOUT,
|
||||
AIOHTTP_NEEDS_CLEANUP_CLOSED,
|
||||
AIOHTTP_TTL_DNS_CACHE,
|
||||
COMPLETION_HTTP_FALLBACK_SECONDS,
|
||||
DEFAULT_SSL_CIPHERS,
|
||||
HTTP_HANDLER_CONNECT_TIMEOUT_SECONDS,
|
||||
)
|
||||
from litellm.litellm_core_utils.logging_utils import track_llm_api_timing
|
||||
from litellm.types.llms.custom_http import *
|
||||
|
|
@ -70,7 +72,10 @@ def get_default_headers() -> dict:
|
|||
headers = get_default_headers()
|
||||
|
||||
# https://www.python-httpx.org/advanced/timeouts
|
||||
_DEFAULT_TIMEOUT = httpx.Timeout(timeout=5.0, connect=5.0)
|
||||
_DEFAULT_TIMEOUT = httpx.Timeout(
|
||||
timeout=COMPLETION_HTTP_FALLBACK_SECONDS,
|
||||
connect=HTTP_HANDLER_CONNECT_TIMEOUT_SECONDS,
|
||||
)
|
||||
|
||||
|
||||
def _prepare_request_data_and_content(
|
||||
|
|
@ -316,30 +321,95 @@ def mask_sensitive_info(error_message):
|
|||
return error_message
|
||||
|
||||
|
||||
def _safe_get_response_text(response: httpx.Response) -> str:
|
||||
"""Safely read response text, falling back to empty string on decoding errors."""
|
||||
try:
|
||||
return response.text
|
||||
except Exception:
|
||||
return ""
|
||||
|
||||
|
||||
async def _safe_aread_response(response: httpx.Response) -> bytes:
|
||||
"""Safely read async response body, falling back to empty bytes on errors."""
|
||||
try:
|
||||
return await response.aread()
|
||||
except Exception:
|
||||
return b""
|
||||
|
||||
|
||||
def _safe_read_response(response: httpx.Response) -> bytes:
|
||||
"""Safely read sync response body, falling back to empty bytes on errors."""
|
||||
try:
|
||||
return response.read()
|
||||
except Exception:
|
||||
return b""
|
||||
|
||||
|
||||
def _raise_masked_sync_error(e: httpx.HTTPStatusError, stream: bool) -> None:
|
||||
"""Raise a MaskedHTTPStatusError for sync HTTP handlers."""
|
||||
if stream:
|
||||
_body = mask_sensitive_info(_safe_read_response(e.response))
|
||||
raise MaskedHTTPStatusError(e, message=_body, text=_body) from None
|
||||
_text = mask_sensitive_info(_safe_get_response_text(e.response))
|
||||
raise MaskedHTTPStatusError(e, message=_text, text=_text) from None
|
||||
|
||||
|
||||
async def _raise_masked_async_error(e: httpx.HTTPStatusError, stream: bool) -> None:
|
||||
"""Raise a MaskedHTTPStatusError for async HTTP handlers."""
|
||||
if stream:
|
||||
_body = mask_sensitive_info(await _safe_aread_response(e.response))
|
||||
raise MaskedHTTPStatusError(e, message=_body, text=_body) from None
|
||||
_text = mask_sensitive_info(_safe_get_response_text(e.response))
|
||||
raise MaskedHTTPStatusError(e, message=_text, text=_text) from None
|
||||
|
||||
|
||||
class MaskedHTTPStatusError(httpx.HTTPStatusError):
|
||||
def __init__(
|
||||
self, original_error, message: Optional[str] = None, text: Optional[str] = None
|
||||
):
|
||||
# Create a new error with the masked URL
|
||||
masked_url = mask_sensitive_info(str(original_error.request.url))
|
||||
# Create a new error that looks like the original, but with a masked URL
|
||||
# Mask the original exception message too (it contains the full URL)
|
||||
masked_original_message = mask_sensitive_info(str(original_error))
|
||||
|
||||
# Safely access response content — decompression can fail (e.g. zlib error).
|
||||
# `.content` returns already-decoded bytes, so we must strip transport
|
||||
# encoding headers before rebuilding the Response (otherwise httpx will
|
||||
# try to decode the bytes a second time and raise DecodingError).
|
||||
try:
|
||||
response_content = original_error.response.content
|
||||
except Exception:
|
||||
response_content = b""
|
||||
|
||||
response_headers = {
|
||||
k: v
|
||||
for k, v in original_error.response.headers.items()
|
||||
if k.lower() not in ("content-encoding", "content-length")
|
||||
}
|
||||
|
||||
masked_request = httpx.Request(
|
||||
method=original_error.request.method,
|
||||
url=masked_url,
|
||||
headers=original_error.request.headers,
|
||||
content=original_error.request.content,
|
||||
)
|
||||
|
||||
super().__init__(
|
||||
message=original_error.message,
|
||||
request=httpx.Request(
|
||||
method=original_error.request.method,
|
||||
url=masked_url,
|
||||
headers=original_error.request.headers,
|
||||
content=original_error.request.content,
|
||||
),
|
||||
message=masked_original_message,
|
||||
request=masked_request,
|
||||
# Attach the masked request so `response.request` is set — otherwise
|
||||
# downstream code that inspects err.response.request (e.g.
|
||||
# exception_mapping_utils) hits `RuntimeError: .request not set`.
|
||||
response=httpx.Response(
|
||||
status_code=original_error.response.status_code,
|
||||
content=original_error.response.content,
|
||||
headers=original_error.response.headers,
|
||||
content=response_content,
|
||||
headers=response_headers,
|
||||
request=masked_request,
|
||||
),
|
||||
)
|
||||
self.message = message
|
||||
self.text = text
|
||||
self.status_code = original_error.response.status_code
|
||||
|
||||
|
||||
class AsyncHTTPHandler:
|
||||
|
|
@ -501,16 +571,7 @@ class AsyncHTTPHandler:
|
|||
headers=headers,
|
||||
)
|
||||
except httpx.HTTPStatusError as e:
|
||||
if stream is True:
|
||||
setattr(e, "message", await e.response.aread())
|
||||
setattr(e, "text", await e.response.aread())
|
||||
else:
|
||||
setattr(e, "message", mask_sensitive_info(e.response.text))
|
||||
setattr(e, "text", mask_sensitive_info(e.response.text))
|
||||
|
||||
setattr(e, "status_code", e.response.status_code)
|
||||
|
||||
raise e
|
||||
await _raise_masked_async_error(e, stream)
|
||||
except Exception as e:
|
||||
raise e
|
||||
|
||||
|
|
@ -571,12 +632,7 @@ class AsyncHTTPHandler:
|
|||
headers=headers,
|
||||
)
|
||||
except httpx.HTTPStatusError as e:
|
||||
setattr(e, "status_code", e.response.status_code)
|
||||
if stream is True:
|
||||
setattr(e, "message", await e.response.aread())
|
||||
else:
|
||||
setattr(e, "message", e.response.text)
|
||||
raise e
|
||||
await _raise_masked_async_error(e, stream)
|
||||
except Exception as e:
|
||||
raise e
|
||||
|
||||
|
|
@ -637,12 +693,7 @@ class AsyncHTTPHandler:
|
|||
headers=headers,
|
||||
)
|
||||
except httpx.HTTPStatusError as e:
|
||||
setattr(e, "status_code", e.response.status_code)
|
||||
if stream is True:
|
||||
setattr(e, "message", await e.response.aread())
|
||||
else:
|
||||
setattr(e, "message", e.response.text)
|
||||
raise e
|
||||
await _raise_masked_async_error(e, stream)
|
||||
except Exception as e:
|
||||
raise e
|
||||
|
||||
|
|
@ -690,12 +741,7 @@ class AsyncHTTPHandler:
|
|||
finally:
|
||||
await new_client.aclose()
|
||||
except httpx.HTTPStatusError as e:
|
||||
setattr(e, "status_code", e.response.status_code)
|
||||
if stream is True:
|
||||
setattr(e, "message", await e.response.aread())
|
||||
else:
|
||||
setattr(e, "message", e.response.text)
|
||||
raise e
|
||||
await _raise_masked_async_error(e, stream)
|
||||
except Exception as e:
|
||||
raise e
|
||||
|
||||
|
|
@ -886,9 +932,9 @@ class AsyncHTTPHandler:
|
|||
if AIOHTTP_CONNECTOR_LIMIT > 0:
|
||||
transport_connector_kwargs["limit"] = AIOHTTP_CONNECTOR_LIMIT
|
||||
if AIOHTTP_CONNECTOR_LIMIT_PER_HOST > 0:
|
||||
transport_connector_kwargs[
|
||||
"limit_per_host"
|
||||
] = AIOHTTP_CONNECTOR_LIMIT_PER_HOST
|
||||
transport_connector_kwargs["limit_per_host"] = (
|
||||
AIOHTTP_CONNECTOR_LIMIT_PER_HOST
|
||||
)
|
||||
|
||||
return LiteLLMAiohttpTransport(
|
||||
client=lambda: ClientSession(
|
||||
|
|
@ -1035,16 +1081,7 @@ class HTTPHandler:
|
|||
llm_provider="litellm-httpx-handler",
|
||||
)
|
||||
except httpx.HTTPStatusError as e:
|
||||
if stream is True:
|
||||
setattr(e, "message", mask_sensitive_info(e.response.read()))
|
||||
setattr(e, "text", mask_sensitive_info(e.response.read()))
|
||||
else:
|
||||
error_text = mask_sensitive_info(e.response.text)
|
||||
setattr(e, "message", error_text)
|
||||
setattr(e, "text", error_text)
|
||||
|
||||
setattr(e, "status_code", e.response.status_code)
|
||||
raise e
|
||||
_raise_masked_sync_error(e, stream)
|
||||
except Exception as e:
|
||||
raise e
|
||||
|
||||
|
|
@ -1083,17 +1120,7 @@ class HTTPHandler:
|
|||
llm_provider="litellm-httpx-handler",
|
||||
)
|
||||
except httpx.HTTPStatusError as e:
|
||||
if stream is True:
|
||||
setattr(e, "message", mask_sensitive_info(e.response.read()))
|
||||
setattr(e, "text", mask_sensitive_info(e.response.read()))
|
||||
else:
|
||||
error_text = mask_sensitive_info(e.response.text)
|
||||
setattr(e, "message", error_text)
|
||||
setattr(e, "text", error_text)
|
||||
|
||||
setattr(e, "status_code", e.response.status_code)
|
||||
|
||||
raise e
|
||||
_raise_masked_sync_error(e, stream)
|
||||
except Exception as e:
|
||||
raise e
|
||||
|
||||
|
|
@ -1130,6 +1157,8 @@ class HTTPHandler:
|
|||
model="default-model-name",
|
||||
llm_provider="litellm-httpx-handler",
|
||||
)
|
||||
except httpx.HTTPStatusError as e:
|
||||
_raise_masked_sync_error(e, stream)
|
||||
except Exception as e:
|
||||
raise e
|
||||
|
||||
|
|
@ -1168,17 +1197,7 @@ class HTTPHandler:
|
|||
llm_provider="litellm-httpx-handler",
|
||||
)
|
||||
except httpx.HTTPStatusError as e:
|
||||
if stream is True:
|
||||
setattr(e, "message", mask_sensitive_info(e.response.read()))
|
||||
setattr(e, "text", mask_sensitive_info(e.response.read()))
|
||||
else:
|
||||
error_text = mask_sensitive_info(e.response.text)
|
||||
setattr(e, "message", error_text)
|
||||
setattr(e, "text", error_text)
|
||||
|
||||
setattr(e, "status_code", e.response.status_code)
|
||||
|
||||
raise e
|
||||
_raise_masked_sync_error(e, stream)
|
||||
except Exception as e:
|
||||
raise e
|
||||
|
||||
|
|
@ -1244,7 +1263,7 @@ def get_async_httpx_client(
|
|||
_new_client = AsyncHTTPHandler(**handler_params)
|
||||
else:
|
||||
_new_client = AsyncHTTPHandler(
|
||||
timeout=httpx.Timeout(timeout=600.0, connect=5.0),
|
||||
timeout=_DEFAULT_TIMEOUT,
|
||||
shared_session=shared_session,
|
||||
)
|
||||
|
||||
|
|
@ -1293,7 +1312,7 @@ def _get_httpx_client(params: Optional[dict] = None) -> HTTPHandler:
|
|||
}
|
||||
_new_client = HTTPHandler(**handler_params)
|
||||
else:
|
||||
_new_client = HTTPHandler(timeout=httpx.Timeout(timeout=600.0, connect=5.0))
|
||||
_new_client = HTTPHandler(timeout=_DEFAULT_TIMEOUT)
|
||||
|
||||
cache.set_cache(
|
||||
key=_cache_key_name,
|
||||
|
|
|
|||
|
|
@ -22,7 +22,7 @@ import litellm
|
|||
import litellm.litellm_core_utils
|
||||
import litellm.types
|
||||
import litellm.types.utils
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm._logging import _redact_string, verbose_logger
|
||||
from litellm.anthropic_beta_headers_manager import update_headers_with_filtered_beta
|
||||
from litellm.constants import REALTIME_WEBSOCKET_MAX_MESSAGE_SIZE_BYTES
|
||||
from litellm.litellm_core_utils.realtime_streaming import RealTimeStreaming
|
||||
|
|
@ -1816,6 +1816,73 @@ class BaseLLMHTTPHandler:
|
|||
logging_obj=logging_obj,
|
||||
)
|
||||
|
||||
async def _async_post_anthropic_messages_with_http_error_retry(
|
||||
self,
|
||||
async_httpx_client: AsyncHTTPHandler,
|
||||
request_url: str,
|
||||
headers: dict,
|
||||
signed_json_body: Optional[bytes],
|
||||
request_body: dict,
|
||||
stream: bool,
|
||||
logging_obj: LiteLLMLoggingObj,
|
||||
provider_config: BaseAnthropicMessagesConfig,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
api_key: Optional[str],
|
||||
model: str,
|
||||
) -> httpx.Response:
|
||||
max_attempts = max(
|
||||
provider_config.max_retry_on_anthropic_messages_http_error, 1
|
||||
)
|
||||
litellm_params_dict = dict(litellm_params)
|
||||
optional_params_dict = dict(litellm_params)
|
||||
for attempt_idx in range(max_attempts):
|
||||
try:
|
||||
response = await async_httpx_client.post(
|
||||
url=request_url,
|
||||
headers=headers,
|
||||
data=signed_json_body or json.dumps(request_body),
|
||||
stream=stream or False,
|
||||
logging_obj=logging_obj,
|
||||
)
|
||||
response.raise_for_status()
|
||||
return response
|
||||
except httpx.HTTPStatusError as e:
|
||||
hit_max_attempt = attempt_idx + 1 == max_attempts
|
||||
should_retry = (
|
||||
provider_config.should_retry_anthropic_messages_on_http_error(
|
||||
e=e, litellm_params=litellm_params_dict
|
||||
)
|
||||
)
|
||||
if should_retry and not hit_max_attempt:
|
||||
verbose_logger.debug(
|
||||
"Anthropic /v1/messages: invalid thinking signature; "
|
||||
"stripping thinking blocks and retrying (attempt %s/%s).",
|
||||
attempt_idx + 2,
|
||||
max_attempts,
|
||||
)
|
||||
provider_config.transform_anthropic_messages_request_on_http_error(
|
||||
e=e, request_data=request_body
|
||||
)
|
||||
headers, signed_json_body = provider_config.sign_request(
|
||||
headers=headers,
|
||||
optional_params=optional_params_dict,
|
||||
request_data=request_body,
|
||||
api_base=request_url,
|
||||
api_key=api_key,
|
||||
stream=stream,
|
||||
fake_stream=False,
|
||||
model=model,
|
||||
)
|
||||
logging_obj.model_call_details.update(request_body)
|
||||
continue
|
||||
raise self._handle_error(e=e, provider_config=provider_config)
|
||||
except Exception as e:
|
||||
raise self._handle_error(e=e, provider_config=provider_config)
|
||||
|
||||
raise RuntimeError(
|
||||
"unreachable: anthropic messages HTTP retry loop exited without return"
|
||||
)
|
||||
|
||||
async def async_anthropic_messages_handler(
|
||||
self,
|
||||
model: str,
|
||||
|
|
@ -1955,19 +2022,19 @@ class BaseLLMHTTPHandler:
|
|||
},
|
||||
)
|
||||
|
||||
try:
|
||||
response = await async_httpx_client.post(
|
||||
url=request_url,
|
||||
headers=headers,
|
||||
data=signed_json_body or json.dumps(request_body),
|
||||
stream=stream or False,
|
||||
logging_obj=logging_obj,
|
||||
)
|
||||
response.raise_for_status()
|
||||
except Exception as e:
|
||||
raise self._handle_error(
|
||||
e=e, provider_config=anthropic_messages_provider_config
|
||||
)
|
||||
response = await self._async_post_anthropic_messages_with_http_error_retry(
|
||||
async_httpx_client=async_httpx_client,
|
||||
request_url=request_url,
|
||||
headers=headers,
|
||||
signed_json_body=signed_json_body,
|
||||
request_body=request_body,
|
||||
stream=stream or False,
|
||||
logging_obj=logging_obj,
|
||||
provider_config=anthropic_messages_provider_config,
|
||||
litellm_params=litellm_params,
|
||||
api_key=api_key,
|
||||
model=model,
|
||||
)
|
||||
|
||||
# used for logging + cost tracking
|
||||
logging_obj.model_call_details["httpx_response"] = response
|
||||
|
|
@ -4496,9 +4563,9 @@ class BaseLLMHTTPHandler:
|
|||
# Second: Execute agentic loop
|
||||
# Add custom_llm_provider to kwargs so the agentic loop can reconstruct the full model name
|
||||
kwargs_with_provider = kwargs.copy() if kwargs else {}
|
||||
kwargs_with_provider[
|
||||
"custom_llm_provider"
|
||||
] = custom_llm_provider
|
||||
kwargs_with_provider["custom_llm_provider"] = (
|
||||
custom_llm_provider
|
||||
)
|
||||
agentic_response = await callback.async_run_agentic_loop(
|
||||
tools=tool_calls,
|
||||
model=model,
|
||||
|
|
@ -4614,9 +4681,9 @@ class BaseLLMHTTPHandler:
|
|||
# Second: Execute agentic loop
|
||||
# Add custom_llm_provider to kwargs so the agentic loop can reconstruct the full model name
|
||||
kwargs_with_provider = kwargs.copy() if kwargs else {}
|
||||
kwargs_with_provider[
|
||||
"custom_llm_provider"
|
||||
] = custom_llm_provider
|
||||
kwargs_with_provider["custom_llm_provider"] = (
|
||||
custom_llm_provider
|
||||
)
|
||||
agentic_response = (
|
||||
await callback.async_run_chat_completion_agentic_loop(
|
||||
tools=tool_calls,
|
||||
|
|
@ -4789,12 +4856,12 @@ class BaseLLMHTTPHandler:
|
|||
|
||||
except websockets.exceptions.InvalidStatusCode as e: # type: ignore
|
||||
verbose_logger.exception(f"Error connecting to backend: {e}")
|
||||
await websocket.close(code=e.status_code, reason=str(e))
|
||||
await websocket.close(code=e.status_code, reason=_redact_string(str(e)))
|
||||
except Exception as e:
|
||||
verbose_logger.exception(f"Error connecting to backend: {e}")
|
||||
try:
|
||||
await websocket.close(
|
||||
code=1011, reason=f"Internal server error: {str(e)}"
|
||||
code=1011, reason=_redact_string(f"Internal server error: {str(e)}")
|
||||
)
|
||||
except RuntimeError as close_error:
|
||||
if "already completed" in str(close_error) or "websocket.close" in str(
|
||||
|
|
@ -5076,12 +5143,12 @@ class BaseLLMHTTPHandler:
|
|||
|
||||
except websockets.exceptions.InvalidStatusCode as e: # type: ignore
|
||||
verbose_logger.exception(f"Error connecting to responses WS backend: {e}")
|
||||
await websocket.close(code=e.status_code, reason=str(e))
|
||||
await websocket.close(code=e.status_code, reason=_redact_string(str(e)))
|
||||
except Exception as e:
|
||||
verbose_logger.exception(f"Error in responses WS: {e}")
|
||||
try:
|
||||
await websocket.close(
|
||||
code=1011, reason=f"Internal server error: {str(e)}"
|
||||
code=1011, reason=_redact_string(f"Internal server error: {str(e)}")
|
||||
)
|
||||
except RuntimeError as close_error:
|
||||
if "already completed" in str(close_error) or "websocket.close" in str(
|
||||
|
|
@ -5110,7 +5177,10 @@ class BaseLLMHTTPHandler:
|
|||
_is_async: bool = False,
|
||||
fake_stream: bool = False,
|
||||
litellm_metadata: Optional[Dict[str, Any]] = None,
|
||||
) -> Union[ImageResponse, Coroutine[Any, Any, ImageResponse],]:
|
||||
) -> Union[
|
||||
ImageResponse,
|
||||
Coroutine[Any, Any, ImageResponse],
|
||||
]:
|
||||
"""
|
||||
|
||||
Handles image edit requests.
|
||||
|
|
@ -5322,7 +5392,10 @@ class BaseLLMHTTPHandler:
|
|||
fake_stream: bool = False,
|
||||
litellm_metadata: Optional[Dict[str, Any]] = None,
|
||||
api_key: Optional[str] = None,
|
||||
) -> Union[ImageResponse, Coroutine[Any, Any, ImageResponse],]:
|
||||
) -> Union[
|
||||
ImageResponse,
|
||||
Coroutine[Any, Any, ImageResponse],
|
||||
]:
|
||||
"""
|
||||
Handles image generation requests.
|
||||
When _is_async=True, returns a coroutine instead of making the call directly.
|
||||
|
|
@ -5562,7 +5635,10 @@ class BaseLLMHTTPHandler:
|
|||
fake_stream: bool = False,
|
||||
litellm_metadata: Optional[Dict[str, Any]] = None,
|
||||
api_key: Optional[str] = None,
|
||||
) -> Union[VideoObject, Coroutine[Any, Any, VideoObject],]:
|
||||
) -> Union[
|
||||
VideoObject,
|
||||
Coroutine[Any, Any, VideoObject],
|
||||
]:
|
||||
"""
|
||||
Handles video generation requests.
|
||||
When _is_async=True, returns a coroutine instead of making the call directly.
|
||||
|
|
|
|||
|
|
@ -28,7 +28,7 @@ class GeminiModelInfo(BaseLLMModelInfo):
|
|||
api_key: Optional[str] = None,
|
||||
api_base: Optional[str] = None,
|
||||
) -> dict:
|
||||
"""Google AI Studio sends api key in query params"""
|
||||
"""Google AI Studio sends api key via x-goog-api-key header"""
|
||||
return headers
|
||||
|
||||
@property
|
||||
|
|
@ -75,7 +75,8 @@ class GeminiModelInfo(BaseLLMModelInfo):
|
|||
)
|
||||
|
||||
response = litellm.module_level_client.get(
|
||||
url=f"{api_base}{endpoint}?key={api_key}",
|
||||
url=f"{api_base}{endpoint}",
|
||||
headers={"x-goog-api-key": api_key},
|
||||
)
|
||||
|
||||
if response.status_code != 200:
|
||||
|
|
|
|||
|
|
@ -86,7 +86,7 @@ class GoogleAIStudioFilesHandler(GeminiModelInfo, BaseFilesConfig):
|
|||
if not final_api_key:
|
||||
raise ValueError("api_key is required")
|
||||
|
||||
url = "{}/{}?key={}".format(api_base, endpoint, final_api_key)
|
||||
url = "{}/{}".format(api_base, endpoint)
|
||||
return url
|
||||
|
||||
def get_supported_openai_params(
|
||||
|
|
@ -231,9 +231,9 @@ class GoogleAIStudioFilesHandler(GeminiModelInfo, BaseFilesConfig):
|
|||
)
|
||||
api_base = api_base.rstrip("/")
|
||||
|
||||
url = f"{api_base}/v1beta/{file_part}?key={api_key}"
|
||||
url = f"{api_base}/v1beta/{file_part}"
|
||||
|
||||
# Return empty params dict - API key is already in URL, no query params needed
|
||||
# API key is passed via x-goog-api-key header (set in validate_environment)
|
||||
return url, {}
|
||||
|
||||
def _normalize_gemini_file_id(self, file_id: str) -> str:
|
||||
|
|
|
|||
|
|
@ -75,9 +75,13 @@ class GoogleAIStudioInteractionsConfig(BaseInteractionsAPIConfig):
|
|||
model: str,
|
||||
litellm_params: Optional[GenericLiteLLMParams],
|
||||
) -> dict:
|
||||
"""Google AI Studio uses API key in query params, not headers."""
|
||||
"""Google AI Studio uses x-goog-api-key header for authentication."""
|
||||
headers = headers or {}
|
||||
headers["Content-Type"] = "application/json"
|
||||
if litellm_params:
|
||||
api_key = GeminiModelInfo.get_api_key(litellm_params.get("api_key"))
|
||||
if api_key:
|
||||
headers["x-goog-api-key"] = api_key
|
||||
return headers
|
||||
|
||||
def get_complete_url(
|
||||
|
|
@ -98,11 +102,10 @@ class GoogleAIStudioInteractionsConfig(BaseInteractionsAPIConfig):
|
|||
"Google API key is required. Set GOOGLE_API_KEY or GEMINI_API_KEY environment variable."
|
||||
)
|
||||
|
||||
query_params = f"key={api_key}"
|
||||
if stream:
|
||||
query_params += "&alt=sse"
|
||||
return f"{api_base}/{self.api_version}/interactions?alt=sse"
|
||||
|
||||
return f"{api_base}/{self.api_version}/interactions?{query_params}"
|
||||
return f"{api_base}/{self.api_version}/interactions"
|
||||
|
||||
def transform_request(
|
||||
self,
|
||||
|
|
@ -200,11 +203,10 @@ class GoogleAIStudioInteractionsConfig(BaseInteractionsAPIConfig):
|
|||
) -> Tuple[str, Dict]:
|
||||
"""GET /{api_version}/interactions/{interaction_id}"""
|
||||
resolved_api_base = GeminiModelInfo.get_api_base(api_base)
|
||||
api_key = GeminiModelInfo.get_api_key(litellm_params.api_key)
|
||||
if not api_key:
|
||||
if not GeminiModelInfo.get_api_key(litellm_params.api_key):
|
||||
raise ValueError("Google API key is required")
|
||||
return (
|
||||
f"{resolved_api_base}/{self.api_version}/interactions/{interaction_id}?key={api_key}",
|
||||
f"{resolved_api_base}/{self.api_version}/interactions/{interaction_id}",
|
||||
{},
|
||||
)
|
||||
|
||||
|
|
@ -234,11 +236,10 @@ class GoogleAIStudioInteractionsConfig(BaseInteractionsAPIConfig):
|
|||
) -> Tuple[str, Dict]:
|
||||
"""DELETE /{api_version}/interactions/{interaction_id}"""
|
||||
resolved_api_base = GeminiModelInfo.get_api_base(api_base)
|
||||
api_key = GeminiModelInfo.get_api_key(litellm_params.api_key)
|
||||
if not api_key:
|
||||
if not GeminiModelInfo.get_api_key(litellm_params.api_key):
|
||||
raise ValueError("Google API key is required")
|
||||
return (
|
||||
f"{resolved_api_base}/{self.api_version}/interactions/{interaction_id}?key={api_key}",
|
||||
f"{resolved_api_base}/{self.api_version}/interactions/{interaction_id}",
|
||||
{},
|
||||
)
|
||||
|
||||
|
|
@ -265,11 +266,10 @@ class GoogleAIStudioInteractionsConfig(BaseInteractionsAPIConfig):
|
|||
) -> Tuple[str, Dict]:
|
||||
"""POST /{api_version}/interactions/{interaction_id}:cancel (if supported)"""
|
||||
resolved_api_base = GeminiModelInfo.get_api_base(api_base)
|
||||
api_key = GeminiModelInfo.get_api_key(litellm_params.api_key)
|
||||
if not api_key:
|
||||
if not GeminiModelInfo.get_api_key(litellm_params.api_key):
|
||||
raise ValueError("Google API key is required")
|
||||
return (
|
||||
f"{resolved_api_base}/{self.api_version}/interactions/{interaction_id}:cancel?key={api_key}",
|
||||
f"{resolved_api_base}/{self.api_version}/interactions/{interaction_id}:cancel",
|
||||
{},
|
||||
)
|
||||
|
||||
|
|
|
|||
|
|
@ -85,6 +85,10 @@ class GeminiRealtimeConfig(BaseRealtimeConfig):
|
|||
raise ValueError("api_key is required for Gemini API calls")
|
||||
api_base = api_base.replace("https://", "wss://")
|
||||
api_base = api_base.replace("http://", "ws://")
|
||||
# WebSocket connections do not support custom HTTP headers in all clients,
|
||||
# so the API key must remain as a query parameter here. This is an accepted
|
||||
# limitation; httpx is not used for WebSocket so MaskedHTTPStatusError
|
||||
# already covers the main leak vector.
|
||||
return f"{api_base}/ws/google.ai.generativelanguage.v1beta.GenerativeService.BidiGenerateContent?key={api_key}"
|
||||
|
||||
def map_model_turn_event(
|
||||
|
|
|
|||
|
|
@ -48,7 +48,7 @@ class GeminiVectorStoreConfig(BaseVectorStoreConfig):
|
|||
def get_auth_credentials(
|
||||
self, litellm_params: dict
|
||||
) -> BaseVectorStoreAuthCredentials:
|
||||
"""Gemini uses API key in query params, not headers."""
|
||||
"""Gemini uses x-goog-api-key header for authentication."""
|
||||
return {}
|
||||
|
||||
def get_vector_store_endpoints_by_type(self) -> VectorStoreIndexEndpoints:
|
||||
|
|
@ -79,6 +79,7 @@ class GeminiVectorStoreConfig(BaseVectorStoreConfig):
|
|||
api_key = litellm_params.get("api_key") or get_api_key_from_env()
|
||||
if api_key:
|
||||
self._cached_api_key = api_key
|
||||
headers["x-goog-api-key"] = api_key
|
||||
|
||||
return headers
|
||||
|
||||
|
|
@ -133,13 +134,10 @@ class GeminiVectorStoreConfig(BaseVectorStoreConfig):
|
|||
if model and model.startswith("gemini/"):
|
||||
model = model.replace("gemini/", "")
|
||||
|
||||
# Get API key - Gemini requires it as a query parameter
|
||||
api_key = litellm_params.get("api_key") or GeminiModelInfo.get_api_key()
|
||||
if not api_key:
|
||||
raise ValueError("GEMINI_API_KEY or GOOGLE_API_KEY is required")
|
||||
|
||||
# Build the URL for generateContent with API key
|
||||
url = f"{api_base}/models/{model}:generateContent?key={api_key}"
|
||||
url = f"{api_base}/models/{model}:generateContent"
|
||||
|
||||
# Build file_search tool configuration (using snake_case as per Gemini docs)
|
||||
file_search_config: Dict[str, Any] = {
|
||||
|
|
@ -286,10 +284,7 @@ class GeminiVectorStoreConfig(BaseVectorStoreConfig):
|
|||
"""
|
||||
url = f"{api_base}/fileSearchStores"
|
||||
|
||||
# Append API key as query parameter (required by Gemini)
|
||||
api_key = self._cached_api_key or get_api_key_from_env()
|
||||
if api_key:
|
||||
url = f"{url}?key={api_key}"
|
||||
# API key is passed via x-goog-api-key header (set in validate_environment)
|
||||
|
||||
request_body: Dict[str, Any] = {}
|
||||
|
||||
|
|
|
|||
|
|
@ -54,6 +54,16 @@ def _convert_image_to_gemini_format(image_file) -> Dict[str, str]:
|
|||
return {"bytesBase64Encoded": base64_encoded, "mimeType": mime_type}
|
||||
|
||||
|
||||
def _usage_video_resolution_from_parameters(
|
||||
parameters: Dict[str, Any]
|
||||
) -> Optional[str]:
|
||||
"""Normalize Veo ``parameters.resolution`` for usage and cost tracking."""
|
||||
res = parameters.get("resolution")
|
||||
if res is None or res == "":
|
||||
return None
|
||||
return str(res).strip().lower()
|
||||
|
||||
|
||||
class GeminiVideoConfig(BaseVideoConfig):
|
||||
"""
|
||||
Configuration class for Gemini (Veo) video generation.
|
||||
|
|
@ -65,6 +75,13 @@ class GeminiVideoConfig(BaseVideoConfig):
|
|||
4. Download video using file API
|
||||
"""
|
||||
|
||||
_OPENAI_VIDEO_SIZE_TO_ASPECT_RATIO: Dict[str, str] = {
|
||||
"1280x720": "16:9",
|
||||
"1920x1080": "16:9",
|
||||
"720x1280": "9:16",
|
||||
"1080x1920": "9:16",
|
||||
}
|
||||
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
|
||||
|
|
@ -88,6 +105,8 @@ class GeminiVideoConfig(BaseVideoConfig):
|
|||
- prompt → prompt
|
||||
- input_reference → image
|
||||
- size → aspectRatio (e.g., "1280x720" → "16:9")
|
||||
- size → resolution when inferable ("1280x720"/"720x1280" → "720p",
|
||||
"1920x1080"/"1080x1920" → "1080p"); skipped if ``resolution`` is already set
|
||||
- seconds → durationSeconds (defaults to 4 seconds if not provided)
|
||||
|
||||
All other params are passed through as-is to support Gemini-specific parameters.
|
||||
|
|
@ -113,6 +132,10 @@ class GeminiVideoConfig(BaseVideoConfig):
|
|||
aspect_ratio = self._convert_size_to_aspect_ratio(size)
|
||||
if aspect_ratio:
|
||||
mapped_params["aspectRatio"] = aspect_ratio
|
||||
if not video_create_optional_params.get("resolution"):
|
||||
inferred_resolution = self._convert_size_to_resolution(size)
|
||||
if inferred_resolution is not None:
|
||||
mapped_params["resolution"] = inferred_resolution
|
||||
|
||||
# Map seconds to durationSeconds, default to 4 seconds (matching OpenAI)
|
||||
if "seconds" in video_create_optional_params:
|
||||
|
|
@ -143,14 +166,27 @@ class GeminiVideoConfig(BaseVideoConfig):
|
|||
if not size:
|
||||
return None
|
||||
|
||||
aspect_ratio_map = {
|
||||
"1280x720": "16:9",
|
||||
"1920x1080": "16:9",
|
||||
"720x1280": "9:16",
|
||||
"1080x1920": "9:16",
|
||||
}
|
||||
return self._OPENAI_VIDEO_SIZE_TO_ASPECT_RATIO.get(size, "16:9")
|
||||
|
||||
return aspect_ratio_map.get(size, "16:9")
|
||||
def _convert_size_to_resolution(self, size: str) -> Optional[str]:
|
||||
"""
|
||||
Map OpenAI ``size`` (WxH) to Veo ``resolution`` for presets in
|
||||
``_OPENAI_VIDEO_SIZE_TO_ASPECT_RATIO`` (720p / 1080p from the smaller edge).
|
||||
|
||||
Unknown sizes return None so the API default applies (no forced resolution).
|
||||
"""
|
||||
if not size or size not in self._OPENAI_VIDEO_SIZE_TO_ASPECT_RATIO:
|
||||
return None
|
||||
try:
|
||||
w_str, h_str = size.split("x", 1)
|
||||
smaller = min(int(w_str), int(h_str))
|
||||
except (ValueError, TypeError):
|
||||
return None
|
||||
if smaller == 720:
|
||||
return "720p"
|
||||
if smaller == 1080:
|
||||
return "1080p"
|
||||
return None
|
||||
|
||||
def validate_environment(
|
||||
self,
|
||||
|
|
@ -279,7 +315,7 @@ class GeminiVideoConfig(BaseVideoConfig):
|
|||
We return this as a VideoObject with:
|
||||
- id: operation name (used for polling)
|
||||
- status: "processing"
|
||||
- usage: includes duration_seconds for cost calculation
|
||||
- usage: includes duration_seconds and optional video_resolution for cost calculation
|
||||
"""
|
||||
response_data = raw_response.json()
|
||||
|
||||
|
|
@ -307,7 +343,7 @@ class GeminiVideoConfig(BaseVideoConfig):
|
|||
model=model,
|
||||
)
|
||||
|
||||
usage_data = {}
|
||||
usage_data: Dict[str, Any] = {}
|
||||
if request_data:
|
||||
parameters = request_data.get("parameters", {})
|
||||
duration = (
|
||||
|
|
@ -319,6 +355,9 @@ class GeminiVideoConfig(BaseVideoConfig):
|
|||
usage_data["duration_seconds"] = float(duration)
|
||||
except (ValueError, TypeError):
|
||||
pass
|
||||
video_resolution = _usage_video_resolution_from_parameters(parameters)
|
||||
if video_resolution is not None:
|
||||
usage_data["video_resolution"] = video_resolution
|
||||
|
||||
video_obj.usage = usage_data
|
||||
return video_obj
|
||||
|
|
|
|||
|
|
@ -16,6 +16,7 @@ from httpx._models import Headers, Response
|
|||
from pydantic import BaseModel
|
||||
|
||||
import litellm
|
||||
from litellm.litellm_core_utils.core_helpers import map_finish_reason
|
||||
from litellm.litellm_core_utils.prompt_templates.common_utils import (
|
||||
_extract_reasoning_content,
|
||||
convert_content_list_to_str,
|
||||
|
|
@ -349,7 +350,8 @@ class OllamaChatConfig(BaseConfig):
|
|||
response_json = raw_response.json()
|
||||
|
||||
## RESPONSE OBJECT
|
||||
model_response.choices[0].finish_reason = "stop"
|
||||
_done_reason = map_finish_reason(response_json.get("done_reason") or "stop")
|
||||
model_response.choices[0].finish_reason = _done_reason
|
||||
response_json_message = response_json.get("message")
|
||||
if response_json_message is not None:
|
||||
if "thinking" in response_json_message:
|
||||
|
|
@ -535,7 +537,7 @@ class OllamaChatCompletionResponseIterator(BaseModelResponseIterator):
|
|||
)
|
||||
|
||||
if chunk["done"] is True:
|
||||
finish_reason = chunk.get("done_reason", "stop")
|
||||
finish_reason = chunk.get("done_reason") or "stop"
|
||||
# Override finish_reason when tool_calls are present
|
||||
# Fixes: https://github.com/BerriAI/litellm/issues/18922
|
||||
if tool_calls is not None:
|
||||
|
|
|
|||
|
|
@ -3,7 +3,7 @@ Helper util for handling openai-specific cost calculation
|
|||
- e.g.: prompt caching
|
||||
"""
|
||||
|
||||
from typing import Literal, Optional, Tuple
|
||||
from typing import Any, Literal, Mapping, Optional, Tuple
|
||||
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.litellm_core_utils.llm_cost_calc.utils import generic_cost_per_token
|
||||
|
|
@ -128,11 +128,55 @@ def cost_per_second(
|
|||
return prompt_cost, completion_cost
|
||||
|
||||
|
||||
def _video_resolution_to_cost_field_suffix(resolution: str) -> Optional[str]:
|
||||
"""
|
||||
Map usage resolution to a safe suffix for ``output_cost_per_second_<suffix>`` keys.
|
||||
|
||||
Note: Currently only ``output_cost_per_second_1080p`` is explicitly declared in
|
||||
ModelInfo (types/utils.py). Other resolution tiers (e.g., 720p, 4k) can be added
|
||||
to model_prices_and_context_window.json but are not exposed via get_model_info()
|
||||
until added to the ModelInfo TypedDict.
|
||||
"""
|
||||
r = resolution.strip().lower()
|
||||
if not r:
|
||||
return None
|
||||
safe = "".join(c for c in r if c.isalnum() or c == "_")
|
||||
if not safe or len(safe) > 24:
|
||||
return None
|
||||
return safe
|
||||
|
||||
|
||||
def _video_output_cost_per_second(
|
||||
model_info: Mapping[str, Any],
|
||||
video_resolution: Optional[str],
|
||||
) -> Optional[float]:
|
||||
"""
|
||||
Per-second video output rate from model_info.
|
||||
|
||||
If ``video_resolution`` is set (e.g. ``1080p``, ``720p``, ``4k``), looks up
|
||||
``output_cost_per_second_<resolution>`` first (e.g. ``output_cost_per_second_1080p``),
|
||||
then falls back to ``output_cost_per_second``.
|
||||
"""
|
||||
r = (video_resolution or "").strip().lower()
|
||||
if r:
|
||||
suffix = _video_resolution_to_cost_field_suffix(r)
|
||||
if suffix is not None:
|
||||
tier_key = f"output_cost_per_second_{suffix}"
|
||||
tier_rate = model_info.get(tier_key)
|
||||
if tier_rate is not None:
|
||||
return float(tier_rate)
|
||||
out = model_info.get("output_cost_per_second")
|
||||
if out is not None:
|
||||
return float(out)
|
||||
return None
|
||||
|
||||
|
||||
def video_generation_cost(
|
||||
model: str,
|
||||
duration_seconds: float,
|
||||
custom_llm_provider: Optional[str] = None,
|
||||
model_info: Optional[ModelInfo] = None,
|
||||
video_resolution: Optional[str] = None,
|
||||
) -> float:
|
||||
"""
|
||||
Calculates the cost for video generation based on duration in seconds.
|
||||
|
|
@ -144,6 +188,7 @@ def video_generation_cost(
|
|||
- model_info: Optional[dict], deployment-level model info containing
|
||||
custom video pricing. When provided, skips the global
|
||||
get_model_info() lookup so that deployment-specific pricing is used.
|
||||
- video_resolution: Optional resolution label from usage (e.g. ``720p``, ``1080p``).
|
||||
|
||||
Returns:
|
||||
float - total_cost_in_usd
|
||||
|
|
@ -162,8 +207,7 @@ def video_generation_cost(
|
|||
)
|
||||
return video_cost_per_second * duration_seconds
|
||||
|
||||
# Fallback to general output cost per second
|
||||
output_cost_per_second = model_info.get("output_cost_per_second")
|
||||
output_cost_per_second = _video_output_cost_per_second(model_info, video_resolution)
|
||||
if output_cost_per_second is not None:
|
||||
verbose_logger.debug(
|
||||
f"For model={model} - output_cost_per_second: {output_cost_per_second}; duration: {duration_seconds}"
|
||||
|
|
|
|||
|
|
@ -6,6 +6,7 @@ This requires websockets, and is currently only supported on LiteLLM Proxy.
|
|||
|
||||
from typing import Any, Optional, cast
|
||||
|
||||
from litellm._logging import _redact_string
|
||||
from litellm.constants import REALTIME_WEBSOCKET_MAX_MESSAGE_SIZE_BYTES
|
||||
from litellm.types.realtime import RealtimeQueryParams
|
||||
|
||||
|
|
@ -148,11 +149,11 @@ class OpenAIRealtime(OpenAIChatCompletion):
|
|||
await realtime_streaming.bidirectional_forward()
|
||||
|
||||
except websockets.exceptions.InvalidStatusCode as e: # type: ignore
|
||||
await websocket.close(code=e.status_code, reason=str(e))
|
||||
await websocket.close(code=e.status_code, reason=_redact_string(str(e)))
|
||||
except Exception as e:
|
||||
try:
|
||||
await websocket.close(
|
||||
code=1011, reason=f"Internal server error: {str(e)}"
|
||||
code=1011, reason=_redact_string(f"Internal server error: {str(e)}")
|
||||
)
|
||||
except RuntimeError as close_error:
|
||||
if "already completed" in str(close_error) or "websocket.close" in str(
|
||||
|
|
|
|||
|
|
@ -8,7 +8,7 @@ Docs: https://docs.together.ai/reference/completions-1
|
|||
|
||||
from typing import Optional
|
||||
|
||||
from litellm.utils import get_model_info
|
||||
from litellm.utils import supports_function_calling
|
||||
from litellm._logging import verbose_logger
|
||||
|
||||
from ..openai.chat.gpt_transformation import OpenAIGPTConfig
|
||||
|
|
@ -21,18 +21,23 @@ class TogetherAIConfig(OpenAIGPTConfig):
|
|||
|
||||
Docs: https://docs.together.ai/docs/json-mode
|
||||
"""
|
||||
supports_function_calling: Optional[bool] = None
|
||||
# Use supports_function_calling() — which reads _get_model_info_helper
|
||||
# directly — instead of get_model_info(). get_model_info() calls
|
||||
# get_supported_openai_params() as its first step, which routes back
|
||||
# into this method for together_ai models, creating a recursion that
|
||||
# only terminates when Python's recursion limit or the "not mapped"
|
||||
# exception in _get_model_info_helper is hit (~332 deep calls).
|
||||
supports_fc: Optional[bool] = None
|
||||
try:
|
||||
model_info = get_model_info(model, custom_llm_provider="together_ai")
|
||||
supports_function_calling = model_info.get(
|
||||
"supports_function_calling", False
|
||||
supports_fc = supports_function_calling(
|
||||
model, custom_llm_provider="together_ai"
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_logger.debug(f"Error getting supported openai params: {e}")
|
||||
pass
|
||||
|
||||
optional_params = super().get_supported_openai_params(model)
|
||||
if supports_function_calling is not True:
|
||||
if supports_fc is not True:
|
||||
verbose_logger.debug(
|
||||
"Only some together models support function calling/response_format. Docs - https://docs.together.ai/docs/function-calling"
|
||||
)
|
||||
|
|
|
|||
|
|
@ -337,8 +337,13 @@ def _get_gemini_url(
|
|||
mode: all_gemini_url_modes,
|
||||
model: str,
|
||||
stream: Optional[bool],
|
||||
gemini_api_key: Optional[str],
|
||||
) -> Tuple[str, str]:
|
||||
"""Build the Gemini API URL for the given mode.
|
||||
|
||||
The API key is NOT included in the URL. Callers must pass it via the
|
||||
``x-goog-api-key`` header instead to avoid leaking credentials in
|
||||
error tracebacks.
|
||||
"""
|
||||
from litellm.llms.vertex_ai.gemini.vertex_and_google_ai_studio_gemini import (
|
||||
VertexGeminiConfig,
|
||||
)
|
||||
|
|
@ -352,27 +357,27 @@ def _get_gemini_url(
|
|||
endpoint = "generateContent"
|
||||
if stream is True:
|
||||
endpoint = "streamGenerateContent"
|
||||
url = "https://generativelanguage.googleapis.com/{}/{}:{}?key={}&alt=sse".format(
|
||||
api_version, _gemini_model_name, endpoint, gemini_api_key
|
||||
url = "https://generativelanguage.googleapis.com/{}/{}:{}?alt=sse".format(
|
||||
api_version, _gemini_model_name, endpoint
|
||||
)
|
||||
else:
|
||||
url = "https://generativelanguage.googleapis.com/{}/{}:{}?key={}".format(
|
||||
api_version, _gemini_model_name, endpoint, gemini_api_key
|
||||
url = "https://generativelanguage.googleapis.com/{}/{}:{}".format(
|
||||
api_version, _gemini_model_name, endpoint
|
||||
)
|
||||
elif mode == "embedding":
|
||||
endpoint = "embedContent"
|
||||
url = "https://generativelanguage.googleapis.com/v1beta/{}:{}?key={}".format(
|
||||
_gemini_model_name, endpoint, gemini_api_key
|
||||
url = "https://generativelanguage.googleapis.com/v1beta/{}:{}".format(
|
||||
_gemini_model_name, endpoint
|
||||
)
|
||||
elif mode == "batch_embedding":
|
||||
endpoint = "batchEmbedContents"
|
||||
url = "https://generativelanguage.googleapis.com/v1beta/{}:{}?key={}".format(
|
||||
_gemini_model_name, endpoint, gemini_api_key
|
||||
url = "https://generativelanguage.googleapis.com/v1beta/{}:{}".format(
|
||||
_gemini_model_name, endpoint
|
||||
)
|
||||
elif mode == "count_tokens":
|
||||
endpoint = "countTokens"
|
||||
url = "https://generativelanguage.googleapis.com/v1beta/{}:{}?key={}".format(
|
||||
_gemini_model_name, endpoint, gemini_api_key
|
||||
url = "https://generativelanguage.googleapis.com/v1beta/{}:{}".format(
|
||||
_gemini_model_name, endpoint
|
||||
)
|
||||
elif mode == "image_generation":
|
||||
raise ValueError(
|
||||
|
|
|
|||
|
|
@ -61,12 +61,11 @@ class ContextCachingEndpoints(VertexBase):
|
|||
Returns
|
||||
token, url
|
||||
"""
|
||||
auth_header: Optional[str]
|
||||
if custom_llm_provider == "gemini":
|
||||
auth_header = None
|
||||
auth_header = {"x-goog-api-key": gemini_api_key} # type: ignore[assignment]
|
||||
endpoint = "cachedContents"
|
||||
url = "https://generativelanguage.googleapis.com/v1beta/{}?key={}".format(
|
||||
endpoint, gemini_api_key
|
||||
)
|
||||
url = "https://generativelanguage.googleapis.com/v1beta/{}".format(endpoint)
|
||||
elif custom_llm_provider == "vertex_ai":
|
||||
auth_header = vertex_auth_header
|
||||
endpoint = "cachedContents"
|
||||
|
|
@ -93,9 +92,9 @@ class ContextCachingEndpoints(VertexBase):
|
|||
model=model,
|
||||
vertex_project=vertex_project,
|
||||
vertex_location=vertex_location,
|
||||
vertex_api_version="v1beta1"
|
||||
if custom_llm_provider == "vertex_ai_beta"
|
||||
else "v1",
|
||||
vertex_api_version=(
|
||||
"v1beta1" if custom_llm_provider == "vertex_ai_beta" else "v1"
|
||||
),
|
||||
)
|
||||
|
||||
def check_cache(
|
||||
|
|
@ -353,7 +352,9 @@ class ContextCachingEndpoints(VertexBase):
|
|||
headers = {
|
||||
"Content-Type": "application/json",
|
||||
}
|
||||
if token is not None:
|
||||
if isinstance(token, dict):
|
||||
headers.update(token)
|
||||
elif token is not None:
|
||||
headers["Authorization"] = f"Bearer {token}"
|
||||
if extra_headers is not None:
|
||||
headers.update(extra_headers)
|
||||
|
|
@ -501,7 +502,9 @@ class ContextCachingEndpoints(VertexBase):
|
|||
headers = {
|
||||
"Content-Type": "application/json",
|
||||
}
|
||||
if token is not None:
|
||||
if isinstance(token, dict):
|
||||
headers.update(token)
|
||||
elif token is not None:
|
||||
headers["Authorization"] = f"Bearer {token}"
|
||||
if extra_headers is not None:
|
||||
headers.update(extra_headers)
|
||||
|
|
|
|||
|
|
@ -480,6 +480,62 @@ class VertexGeminiConfig(VertexAIBaseConfig, BaseConfig):
|
|||
else:
|
||||
return None
|
||||
|
||||
@staticmethod
|
||||
def _resolve_search_tool_conflict(
|
||||
gtool_func_declarations: list,
|
||||
googleSearch: Optional[dict],
|
||||
googleSearchRetrieval: Optional[dict],
|
||||
enterpriseWebSearch: Optional[dict],
|
||||
urlContext: Optional[dict],
|
||||
optional_params: dict,
|
||||
) -> tuple:
|
||||
"""
|
||||
Resolve Vertex AI constraint: multiple Tool objects in a request must
|
||||
ALL be search tools. When function declarations are mixed with search
|
||||
tools, drop search tools to avoid 400 error.
|
||||
|
||||
Skip when include_server_side_tool_invocations is enabled (Gemini 3+
|
||||
supports tool combination natively).
|
||||
|
||||
Note: code_execution, computerUse, and googleMaps are NOT search tools
|
||||
and CAN coexist with function declarations, so they are preserved.
|
||||
|
||||
Ref: https://github.com/BerriAI/litellm/issues/23337
|
||||
|
||||
Returns:
|
||||
tuple of (googleSearch, googleSearchRetrieval, enterpriseWebSearch, urlContext)
|
||||
"""
|
||||
has_search_tools = any(
|
||||
v is not None
|
||||
for v in [
|
||||
googleSearch,
|
||||
googleSearchRetrieval,
|
||||
enterpriseWebSearch,
|
||||
urlContext,
|
||||
]
|
||||
)
|
||||
server_side_tool_invocations = optional_params.get(
|
||||
"include_server_side_tool_invocations", False
|
||||
)
|
||||
if (
|
||||
gtool_func_declarations
|
||||
and has_search_tools
|
||||
and not server_side_tool_invocations
|
||||
):
|
||||
verbose_logger.warning(
|
||||
"Vertex AI does not support mixing function declarations with "
|
||||
"search tools (googleSearch, enterpriseWebSearch, urlContext, "
|
||||
"googleSearchRetrieval) in the same request. Dropping search "
|
||||
"tools and keeping function declarations. To use search tools, "
|
||||
"send a request without function calling tools."
|
||||
)
|
||||
googleSearch = None
|
||||
googleSearchRetrieval = None
|
||||
enterpriseWebSearch = None
|
||||
urlContext = None
|
||||
|
||||
return googleSearch, googleSearchRetrieval, enterpriseWebSearch, urlContext
|
||||
|
||||
def _map_function( # noqa: PLR0915
|
||||
self, value: List[dict], optional_params: dict
|
||||
) -> List[Tools]:
|
||||
|
|
@ -512,9 +568,9 @@ class VertexGeminiConfig(VertexAIBaseConfig, BaseConfig):
|
|||
value = _remove_strict_from_schema(value)
|
||||
|
||||
for tool in value:
|
||||
openai_function_object: Optional[
|
||||
ChatCompletionToolParamFunctionChunk
|
||||
] = None
|
||||
openai_function_object: Optional[ChatCompletionToolParamFunctionChunk] = (
|
||||
None
|
||||
)
|
||||
if "function" in tool: # tools list
|
||||
_openai_function_object = ChatCompletionToolParamFunctionChunk( # type: ignore
|
||||
**tool["function"]
|
||||
|
|
@ -633,6 +689,20 @@ class VertexGeminiConfig(VertexAIBaseConfig, BaseConfig):
|
|||
# per Vertex AI API spec: "A Tool object should contain exactly one type of Tool"
|
||||
_tools_list: List[Tools] = []
|
||||
|
||||
(
|
||||
googleSearch,
|
||||
googleSearchRetrieval,
|
||||
enterpriseWebSearch,
|
||||
urlContext,
|
||||
) = self._resolve_search_tool_conflict(
|
||||
gtool_func_declarations=gtool_func_declarations,
|
||||
googleSearch=googleSearch,
|
||||
googleSearchRetrieval=googleSearchRetrieval,
|
||||
enterpriseWebSearch=enterpriseWebSearch,
|
||||
urlContext=urlContext,
|
||||
optional_params=optional_params,
|
||||
)
|
||||
|
||||
# Function declarations can be grouped together in one Tool
|
||||
if gtool_func_declarations:
|
||||
func_tool = Tools()
|
||||
|
|
@ -646,15 +716,15 @@ class VertexGeminiConfig(VertexAIBaseConfig, BaseConfig):
|
|||
_tools_list.append(search_tool)
|
||||
if googleSearchRetrieval is not None:
|
||||
retrieval_tool = Tools()
|
||||
retrieval_tool[
|
||||
VertexToolName.GOOGLE_SEARCH_RETRIEVAL.value
|
||||
] = googleSearchRetrieval
|
||||
retrieval_tool[VertexToolName.GOOGLE_SEARCH_RETRIEVAL.value] = (
|
||||
googleSearchRetrieval
|
||||
)
|
||||
_tools_list.append(retrieval_tool)
|
||||
if enterpriseWebSearch is not None:
|
||||
enterprise_tool = Tools()
|
||||
enterprise_tool[
|
||||
VertexToolName.ENTERPRISE_WEB_SEARCH.value
|
||||
] = enterpriseWebSearch
|
||||
enterprise_tool[VertexToolName.ENTERPRISE_WEB_SEARCH.value] = (
|
||||
enterpriseWebSearch
|
||||
)
|
||||
_tools_list.append(enterprise_tool)
|
||||
if code_execution is not None:
|
||||
code_tool = Tools()
|
||||
|
|
@ -1101,16 +1171,16 @@ class VertexGeminiConfig(VertexAIBaseConfig, BaseConfig):
|
|||
param_description="thinking_budget",
|
||||
)
|
||||
if VertexGeminiConfig._is_gemini_3_or_newer(model):
|
||||
optional_params[
|
||||
"thinkingConfig"
|
||||
] = VertexGeminiConfig._map_reasoning_effort_to_thinking_level(
|
||||
effort_value, model
|
||||
optional_params["thinkingConfig"] = (
|
||||
VertexGeminiConfig._map_reasoning_effort_to_thinking_level(
|
||||
effort_value, model
|
||||
)
|
||||
)
|
||||
else:
|
||||
optional_params[
|
||||
"thinkingConfig"
|
||||
] = VertexGeminiConfig._map_reasoning_effort_to_thinking_budget(
|
||||
effort_value, model
|
||||
optional_params["thinkingConfig"] = (
|
||||
VertexGeminiConfig._map_reasoning_effort_to_thinking_budget(
|
||||
effort_value, model
|
||||
)
|
||||
)
|
||||
elif param == "thinking":
|
||||
# Validate no conflict with thinking_level
|
||||
|
|
@ -1119,11 +1189,11 @@ class VertexGeminiConfig(VertexAIBaseConfig, BaseConfig):
|
|||
param_name="thinking",
|
||||
param_description="thinking_budget",
|
||||
)
|
||||
optional_params[
|
||||
"thinkingConfig"
|
||||
] = VertexGeminiConfig._map_thinking_param(
|
||||
cast(AnthropicThinkingParam, value),
|
||||
model=model,
|
||||
optional_params["thinkingConfig"] = (
|
||||
VertexGeminiConfig._map_thinking_param(
|
||||
cast(AnthropicThinkingParam, value),
|
||||
model=model,
|
||||
)
|
||||
)
|
||||
elif param == "modalities" and isinstance(value, list):
|
||||
response_modalities = self.map_response_modalities(value)
|
||||
|
|
@ -1547,10 +1617,10 @@ class VertexGeminiConfig(VertexAIBaseConfig, BaseConfig):
|
|||
_tool_response_chunk["provider_specific_fields"] = { # type: ignore
|
||||
"thought_signature": thought_signature
|
||||
}
|
||||
_tool_response_chunk[
|
||||
"id"
|
||||
] = _encode_tool_call_id_with_signature(
|
||||
_tool_response_chunk["id"] or "", thought_signature
|
||||
_tool_response_chunk["id"] = (
|
||||
_encode_tool_call_id_with_signature(
|
||||
_tool_response_chunk["id"] or "", thought_signature
|
||||
)
|
||||
)
|
||||
_tools.append(_tool_response_chunk)
|
||||
cumulative_tool_call_idx += 1
|
||||
|
|
@ -2397,28 +2467,28 @@ class VertexGeminiConfig(VertexAIBaseConfig, BaseConfig):
|
|||
## ADD METADATA TO RESPONSE ##
|
||||
|
||||
setattr(model_response, "vertex_ai_grounding_metadata", grounding_metadata)
|
||||
model_response._hidden_params[
|
||||
"vertex_ai_grounding_metadata"
|
||||
] = grounding_metadata
|
||||
model_response._hidden_params["vertex_ai_grounding_metadata"] = (
|
||||
grounding_metadata
|
||||
)
|
||||
|
||||
setattr(
|
||||
model_response, "vertex_ai_url_context_metadata", url_context_metadata
|
||||
)
|
||||
|
||||
model_response._hidden_params[
|
||||
"vertex_ai_url_context_metadata"
|
||||
] = url_context_metadata
|
||||
model_response._hidden_params["vertex_ai_url_context_metadata"] = (
|
||||
url_context_metadata
|
||||
)
|
||||
|
||||
setattr(model_response, "vertex_ai_safety_results", safety_ratings)
|
||||
model_response._hidden_params[
|
||||
"vertex_ai_safety_results"
|
||||
] = safety_ratings # older approach - maintaining to prevent regressions
|
||||
model_response._hidden_params["vertex_ai_safety_results"] = (
|
||||
safety_ratings # older approach - maintaining to prevent regressions
|
||||
)
|
||||
|
||||
## ADD CITATION METADATA ##
|
||||
setattr(model_response, "vertex_ai_citation_metadata", citation_metadata)
|
||||
model_response._hidden_params[
|
||||
"vertex_ai_citation_metadata"
|
||||
] = citation_metadata # older approach - maintaining to prevent regressions
|
||||
model_response._hidden_params["vertex_ai_citation_metadata"] = (
|
||||
citation_metadata # older approach - maintaining to prevent regressions
|
||||
)
|
||||
|
||||
## ADD TRAFFIC TYPE ##
|
||||
traffic_type = completion_response.get("usageMetadata", {}).get(
|
||||
|
|
@ -3126,7 +3196,12 @@ class ModelResponseIterator:
|
|||
setattr(model_response, "vertex_ai_safety_ratings", safety_ratings) # type: ignore
|
||||
setattr(model_response, "vertex_ai_citation_metadata", citation_metadata) # type: ignore
|
||||
|
||||
return grounding_metadata, url_context_metadata, safety_ratings, citation_metadata
|
||||
return (
|
||||
grounding_metadata,
|
||||
url_context_metadata,
|
||||
safety_ratings,
|
||||
citation_metadata,
|
||||
)
|
||||
|
||||
def _apply_stream_usage_metadata(
|
||||
self,
|
||||
|
|
@ -3151,9 +3226,9 @@ class ModelResponseIterator:
|
|||
|
||||
traffic_type = processed_chunk.get("usageMetadata", {}).get("trafficType")
|
||||
if traffic_type:
|
||||
model_response._hidden_params.setdefault(
|
||||
"provider_specific_fields", {}
|
||||
)["traffic_type"] = traffic_type
|
||||
model_response._hidden_params.setdefault("provider_specific_fields", {})[
|
||||
"traffic_type"
|
||||
] = traffic_type
|
||||
|
||||
service_tier = self.response_headers.get("x-gemini-service-tier")
|
||||
if service_tier:
|
||||
|
|
|
|||
|
|
@ -292,10 +292,10 @@ def process_response(
|
|||
_predictions: VertexAIBatchEmbeddingsResponseObject,
|
||||
) -> EmbeddingResponse:
|
||||
openai_embeddings: List[Embedding] = []
|
||||
for embedding in _predictions["embeddings"]:
|
||||
for idx, embedding in enumerate(_predictions["embeddings"]):
|
||||
openai_embedding = Embedding(
|
||||
embedding=embedding["values"],
|
||||
index=0,
|
||||
index=idx,
|
||||
object="embedding",
|
||||
)
|
||||
openai_embeddings.append(openai_embedding)
|
||||
|
|
|
|||
|
|
@ -78,6 +78,19 @@ class VertexAIPartnerModelsTokenCounter(VertexBase):
|
|||
|
||||
return endpoint
|
||||
|
||||
@staticmethod
|
||||
def _strip_version_suffix(model: str) -> str:
|
||||
"""
|
||||
Strip version suffixes (e.g. @default, @20251001) from model names.
|
||||
|
||||
The Vertex AI count-tokens endpoint rejects model names that include
|
||||
version suffixes — for example, "claude-sonnet-4-6@default" returns
|
||||
"not supported for token counting" while "claude-sonnet-4-6" works.
|
||||
"""
|
||||
if "@" in model:
|
||||
return model.split("@")[0]
|
||||
return model
|
||||
|
||||
async def handle_count_tokens_request(
|
||||
self,
|
||||
model: str,
|
||||
|
|
@ -98,6 +111,15 @@ class VertexAIPartnerModelsTokenCounter(VertexBase):
|
|||
Raises:
|
||||
ValueError: If required parameters are missing or invalid
|
||||
"""
|
||||
# Strip version suffixes (@default, @20251001, etc.) — the Vertex AI
|
||||
# count-tokens endpoint does not accept versioned model names.
|
||||
model = self._strip_version_suffix(model)
|
||||
if "model" in request_data:
|
||||
request_data = {
|
||||
**request_data,
|
||||
"model": self._strip_version_suffix(request_data["model"]),
|
||||
}
|
||||
|
||||
# Validate request
|
||||
if "messages" not in request_data:
|
||||
raise ValueError("messages required for token counting")
|
||||
|
|
|
|||
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue