mirror of
https://github.com/BerriAI/litellm.git
synced 2026-10-10 03:28:53 +00:00
Merge branch 'main' into litellm_docs_policies
This commit is contained in:
 Ishaan Jaff
GitHub
commit
881343dd1b
184 changed files with 9038 additions and 1079 deletions
|
|
@ -112,6 +112,24 @@ jobs:
|
|||
python -m mypy .
|
||||
cd ..
|
||||
no_output_timeout: 10m
|
||||
|
||||
semgrep:
|
||||
docker:
|
||||
- image: cimg/python:3.12
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
- run:
|
||||
name: Install Semgrep
|
||||
command: pip install semgrep
|
||||
- run:
|
||||
name: Run Semgrep (custom rules only)
|
||||
command: semgrep scan --config .semgrep/rules . --error
|
||||
|
||||
local_testing_part1:
|
||||
docker:
|
||||
- image: cimg/python:3.12
|
||||
|
|
@ -2277,6 +2295,7 @@ jobs:
|
|||
- run: python ./tests/code_coverage_tests/router_code_coverage.py
|
||||
- run: python ./tests/code_coverage_tests/test_chat_completion_imports.py
|
||||
- run: python ./tests/code_coverage_tests/info_log_check.py
|
||||
- run: python ./tests/code_coverage_tests/check_guardrail_apply_decorator.py
|
||||
- run: python ./tests/code_coverage_tests/test_ban_set_verbose.py
|
||||
- run: python ./tests/code_coverage_tests/code_qa_check_tests.py
|
||||
- run: python ./tests/code_coverage_tests/check_get_model_cost_key_performance.py
|
||||
|
|
@ -3801,7 +3820,6 @@ jobs:
|
|||
- run:
|
||||
name: Get new version
|
||||
command: |
|
||||
cd litellm-proxy-extras
|
||||
NEW_VERSION=$(python -c "import toml; print(toml.load('pyproject.toml')['tool']['poetry']['version'])")
|
||||
echo "export NEW_VERSION=$NEW_VERSION" >> $BASH_ENV
|
||||
|
||||
|
|
@ -3826,7 +3844,6 @@ jobs:
|
|||
- run:
|
||||
name: Publish to PyPI
|
||||
command: |
|
||||
cd litellm-proxy-extras
|
||||
echo -e "[pypi]\nusername = $PYPI_PUBLISH_USERNAME\npassword = $PYPI_PUBLISH_PASSWORD" > ~/.pypirc
|
||||
python -m pip install --upgrade pip build twine setuptools wheel
|
||||
rm -rf build dist
|
||||
|
|
@ -3933,6 +3950,9 @@ jobs:
|
|||
image: ubuntu-2204:2023.10.1
|
||||
resource_class: xlarge
|
||||
working_directory: ~/project
|
||||
parameters:
|
||||
browser:
|
||||
type: string
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
|
|
@ -3962,7 +3982,7 @@ jobs:
|
|||
echo "Expires at: $EXPIRES_AT"
|
||||
neon branches create \
|
||||
--project-id $NEON_PROJECT_ID \
|
||||
--name preview/commit-${CIRCLE_SHA1:0:7} \
|
||||
--name preview/commit-${CIRCLE_SHA1:0:7}-<< parameters.browser >> \
|
||||
--expires-at $EXPIRES_AT \
|
||||
--parent br-fancy-paper-ad1olsb3 \
|
||||
--api-key $NEON_API_KEY || true
|
||||
|
|
@ -3972,7 +3992,7 @@ jobs:
|
|||
E2E_UI_TEST_DATABASE_URL=$(neon connection-string \
|
||||
--project-id $NEON_PROJECT_ID \
|
||||
--api-key $NEON_API_KEY \
|
||||
--branch preview/commit-${CIRCLE_SHA1:0:7} \
|
||||
--branch preview/commit-${CIRCLE_SHA1:0:7}-<< parameters.browser >> \
|
||||
--database-name yuneng-trial-db \
|
||||
--role neondb_owner)
|
||||
echo $E2E_UI_TEST_DATABASE_URL
|
||||
|
|
@ -3984,7 +4004,7 @@ jobs:
|
|||
-e UI_USERNAME="admin" \
|
||||
-e UI_PASSWORD="gm" \
|
||||
-e LITELLM_LICENSE=$LITELLM_LICENSE \
|
||||
--name litellm-docker-database \
|
||||
--name litellm-docker-database-<< parameters.browser >> \
|
||||
-v $(pwd)/litellm/proxy/example_config_yaml/simple_config.yaml:/app/config.yaml \
|
||||
litellm-docker-database:ci \
|
||||
--config /app/config.yaml \
|
||||
|
|
@ -4000,7 +4020,7 @@ jobs:
|
|||
sudo rm dockerize-linux-amd64-v0.6.1.tar.gz
|
||||
- run:
|
||||
name: Start outputting logs
|
||||
command: docker logs -f litellm-docker-database
|
||||
command: docker logs -f litellm-docker-database-<< parameters.browser >>
|
||||
background: true
|
||||
- run:
|
||||
name: Wait for app to be ready
|
||||
|
|
@ -4009,6 +4029,7 @@ jobs:
|
|||
name: Run Playwright Tests
|
||||
command: |
|
||||
npx playwright test \
|
||||
--project << parameters.browser >> \
|
||||
--config ui/litellm-dashboard/e2e_tests/playwright.config.ts \
|
||||
--reporter=html \
|
||||
--output=test-results
|
||||
|
|
@ -4115,6 +4136,12 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- semgrep:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- local_testing_part1:
|
||||
filters:
|
||||
branches:
|
||||
|
|
@ -4214,6 +4241,20 @@ workflows:
|
|||
- main
|
||||
- /litellm_.*/
|
||||
- e2e_ui_testing:
|
||||
name: e2e_ui_testing_chromium
|
||||
browser: chromium
|
||||
context: e2e_ui_tests
|
||||
requires:
|
||||
- ui_build
|
||||
- build_docker_database_image
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- e2e_ui_testing:
|
||||
name: e2e_ui_testing_firefox
|
||||
browser: firefox
|
||||
context: e2e_ui_tests
|
||||
requires:
|
||||
- ui_build
|
||||
|
|
@ -4493,6 +4534,7 @@ workflows:
|
|||
- publish_to_pypi:
|
||||
requires:
|
||||
- mypy_linting
|
||||
- semgrep
|
||||
- local_testing_part1
|
||||
- local_testing_part2
|
||||
- build_and_test
|
||||
|
|
@ -4525,7 +4567,8 @@ workflows:
|
|||
- litellm_assistants_api_testing
|
||||
- auth_ui_unit_tests
|
||||
- db_migration_disable_update_check
|
||||
- e2e_ui_testing
|
||||
- e2e_ui_testing_chromium
|
||||
- e2e_ui_testing_firefox
|
||||
- litellm_proxy_unit_testing_key_generation
|
||||
- litellm_proxy_unit_testing_part1
|
||||
- litellm_proxy_unit_testing_part2
|
||||
|
|
|
|||
22
.semgrep/rules/README.md
Normal file
22
.semgrep/rules/README.md
Normal file
|
|
@ -0,0 +1,22 @@
|
|||
# Custom Semgrep rules for LiteLLM
|
||||
|
||||
Add custom rule YAML files here. Semgrep loads all `.yml`/`.yaml` files under this directory.
|
||||
|
||||
**Run only custom rules (CI / fail on findings):**
|
||||
|
||||
```bash
|
||||
semgrep scan --config .semgrep/rules . --error
|
||||
```
|
||||
|
||||
**Run with registry + custom rules:**
|
||||
|
||||
```bash
|
||||
semgrep scan --config auto --config .semgrep/rules .
|
||||
```
|
||||
|
||||
**Layout:**
|
||||
|
||||
- `python/` – Python-specific rules (security, patterns)
|
||||
- Add more subdirs as needed (e.g. `generic/` for language-agnostic rules)
|
||||
|
||||
See [Semgrep rule syntax](https://semgrep.dev/docs/writing-rules/rule-syntax/).
|
||||
14
.semgrep/rules/python/unbounded-memory.yml
Normal file
14
.semgrep/rules/python/unbounded-memory.yml
Normal file
|
|
@ -0,0 +1,14 @@
|
|||
# Unbounded memory growth – data structures without a clear max limit
|
||||
# Can lead to OOM under load.
|
||||
|
||||
rules:
|
||||
- id: unbounded-asyncio-queue
|
||||
message: asyncio.Queue() with no maxsize can grow unbounded. Use asyncio.Queue(maxsize=N) for integrations (e.g. log queues).
|
||||
severity: ERROR
|
||||
languages: [python]
|
||||
pattern-either:
|
||||
- pattern: asyncio.Queue()
|
||||
- pattern: asyncio.Queue(maxsize=0)
|
||||
metadata:
|
||||
category: correctness
|
||||
cwe: "CWE-400: Uncontrolled Resource Consumption"
|
||||
|
|
@ -1,3 +1,36 @@
|
|||
ignore:
|
||||
- vulnerability: CVE-2026-22184
|
||||
reason: no fixed zlib package is available yet in the Wolfi repositories, so this is ignored temporarily until an upstream release exists
|
||||
# Wolfi base image: Python 3.13 and Node from apk have no fixed builds in Wolfi yet / not applicable
|
||||
- vulnerability: CVE-2025-55130
|
||||
reason: Node in Wolfi apk; only used for Admin UI build/prisma
|
||||
- vulnerability: CVE-2025-59465
|
||||
reason: Node in Wolfi apk; only used for Admin UI build/prisma
|
||||
- vulnerability: CVE-2025-55131
|
||||
reason: Node in Wolfi apk; only used for Admin UI build/prisma
|
||||
- vulnerability: CVE-2025-59466
|
||||
reason: Node in Wolfi apk; only used for Admin UI build/prisma
|
||||
- vulnerability: CVE-2026-21637
|
||||
reason: Node in Wolfi apk; only used for Admin UI build/prisma
|
||||
- vulnerability: CVE-2025-55132
|
||||
reason: Node in Wolfi apk; only used for Admin UI build/prisma
|
||||
- vulnerability: GHSA-hx9q-6w63-j58v
|
||||
reason: orjson dumps recursion; allowlisted
|
||||
- vulnerability: GHSA-73rr-hh4g-fpgx
|
||||
reason: diff npm transitive dep; override in package.json, allowlisted
|
||||
- vulnerability: CVE-2026-0865
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
- vulnerability: CVE-2025-15282
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
- vulnerability: CVE-2026-0672
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
- vulnerability: CVE-2025-15366
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
- vulnerability: CVE-2025-15367
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
- vulnerability: CVE-2025-11468
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
- vulnerability: CVE-2025-12781
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
- vulnerability: CVE-2026-1299
|
||||
reason: Python 3.13 in Wolfi base; no fixed apk build yet
|
||||
|
|
|
|||
|
|
@ -140,12 +140,14 @@ run_grype_scans() {
|
|||
"GHSA-34x7-hfp2-rc4v" # node-tar hardlink path traversal - not applicable, tar CLI not exposed in application code
|
||||
"GHSA-r6q2-hw4h-h46w" # node-tar not used by application runtime, Linux-only container, not affect by macOS APFS-specific exploit
|
||||
"GHSA-8rrh-rw8j-w5fx" # wheel is from chainguard and will be handled by then TODO: Remove this after Chainguard updates the wheel
|
||||
"CVE-2025-59465" # We do not use Node in application runtime, only used for building Admin UI
|
||||
"CVE-2025-55131" # We do not use Node in application runtime, only used for building Admin UI
|
||||
"CVE-2025-59466" # We do not use Node in application runtime, only used for building Admin UI
|
||||
"CVE-2025-55130" # We do not use Node in application runtime, only used for building Admin UI
|
||||
"CVE-2025-59467" # We do not use Node in application runtime, only used for building Admin UI
|
||||
"CVE-2026-21637" # We do not use Node in application runtime, only used for building Admin UI
|
||||
"CVE-2025-59465" # Node only used for Admin UI build/prisma
|
||||
"CVE-2025-55131" # Node only used for Admin UI build/prisma
|
||||
"CVE-2025-59466" # Node only used for Admin UI build/prisma
|
||||
"CVE-2025-55130" # Node only used for Admin UI build/prisma
|
||||
"CVE-2025-59467" # Node only used for Admin UI build/prisma
|
||||
"CVE-2026-21637" # Node only used for Admin UI build/prisma
|
||||
"CVE-2025-55132" # Node only used for Admin UI build/prisma
|
||||
"GHSA-hx9q-6w63-j58v" # orjson dumps recursion; allowlisted
|
||||
"CVE-2025-15281" # No fix available yet
|
||||
"CVE-2026-0865" # No fix available yet
|
||||
"CVE-2025-15282" # No fix available yet
|
||||
|
|
|
|||
|
|
@ -16,10 +16,14 @@ Usage:
|
|||
import asyncio
|
||||
import base64
|
||||
import json
|
||||
import os
|
||||
import pyaudio
|
||||
import websockets
|
||||
from typing import Optional
|
||||
|
||||
# Bounded queue size for audio chunks (configurable via env to avoid unbounded memory)
|
||||
AUDIO_QUEUE_MAXSIZE = int(os.getenv("LITELLM_ASYNCIO_QUEUE_MAXSIZE", 10_000))
|
||||
|
||||
# Audio configuration (matching Nova Sonic requirements)
|
||||
INPUT_SAMPLE_RATE = 16000 # Nova Sonic expects 16kHz input
|
||||
OUTPUT_SAMPLE_RATE = 24000 # Nova Sonic outputs 24kHz
|
||||
|
|
@ -40,7 +44,7 @@ class RealtimeClient:
|
|||
self.api_key = api_key
|
||||
self.ws: Optional[websockets.WebSocketClientProtocol] = None
|
||||
self.is_active = False
|
||||
self.audio_queue = asyncio.Queue()
|
||||
self.audio_queue = asyncio.Queue(maxsize=AUDIO_QUEUE_MAXSIZE)
|
||||
self.pyaudio = pyaudio.PyAudio()
|
||||
self.input_stream = None
|
||||
self.output_stream = None
|
||||
|
|
|
|||
95
docs/my-website/blog/model_cost_map_incident/index.md
Normal file
95
docs/my-website/blog/model_cost_map_incident/index.md
Normal file
|
|
@ -0,0 +1,95 @@
|
|||
---
|
||||
slug: model-cost-map-incident
|
||||
title: "Incident Report: Invalid model cost map on main"
|
||||
date: 2026-02-10T10:00:00
|
||||
authors:
|
||||
- name: Ishaan Jaffer
|
||||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/ishaanjaffer/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
tags: [incident-report, stability]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
**Date:** January 27, 2026
|
||||
**Duration:** ~20 minutes
|
||||
**Severity:** Low
|
||||
**Status:** Resolved
|
||||
|
||||
## Summary
|
||||
|
||||
A malformed JSON entry in `model_prices_and_context_window.json` was merged to `main` ([`562f0a0`](https://github.com/BerriAI/litellm/commit/562f0a028251750e3d75386bee0e630d9796d0df)). This caused LiteLLM to silently fall back to a stale local copy of the model cost map. Users on older package versions lost cost tracking for newer models only (e.g. `azure/gpt-5.2`). No LLM calls were blocked.
|
||||
|
||||
- **LLM calls and proxy routing:** No impact.
|
||||
- **Cost tracking:** Impacted for newer models not present in the local backup. Older models were unaffected. The incident lasted ~20 minutes until the commit was reverted.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
---
|
||||
|
||||
## Background
|
||||
|
||||
The model cost map is not in the request path. It is used after the LLM response comes back, inside a try/catch, to calculate spend. A missing entry never blocks a call.
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
A["1. litellm.completion() receives request
|
||||
litellm/main.py"] --> B["2. Route to provider
|
||||
litellm/litellm_core_utils/get_llm_provider_logic.py"]
|
||||
B --> C["3. LLM returns response
|
||||
litellm/main.py"]
|
||||
C --> D["4. Post-call: look up model in cost map
|
||||
litellm/cost_calculator.py"]
|
||||
D -->|"found"| E["5a. Attach cost to response"]
|
||||
D -->|"not found (try/catch)"| F["5b. Log warning, set cost=0"]
|
||||
E --> G["6. Return response to caller"]
|
||||
F --> G
|
||||
|
||||
style D fill:#fff3cd,stroke:#ffc107
|
||||
style F fill:#fff3cd,stroke:#ffc107
|
||||
style E fill:#d4edda,stroke:#28a745
|
||||
style G fill:#d4edda,stroke:#28a745
|
||||
```
|
||||
|
||||
Both paths return a response to the caller. When the cost map lookup fails, the only difference is `cost=0` on that request.
|
||||
|
||||
---
|
||||
|
||||
## Root cause
|
||||
|
||||
LiteLLM fetches the model cost map from GitHub `main` at import time. If the fetch fails, it falls back to a local backup bundled with the package. Before this incident, the fallback was completely silent -- no warning was logged.
|
||||
|
||||
A contributor PR introduced an extra `{` bracket, producing invalid JSON. The remote fetch failed with `JSONDecodeError`, triggering the silent fallback. Users on older package versions had backup files missing newer models.
|
||||
|
||||
**Timeline:**
|
||||
|
||||
1. Malformed JSON merged to `main`
|
||||
2. LiteLLM installations fall back to local backup on next import
|
||||
3. Users report `"This model isn't mapped yet"` for newer models
|
||||
4. Bad commit identified and reverted (~20 minutes)
|
||||
|
||||
---
|
||||
|
||||
## Remediation
|
||||
|
||||
| # | Action | Status | Code |
|
||||
|---|---|---|---|
|
||||
| 1 | CI validation on `model_prices_and_context_window.json` | ✅ Done | [`test-model-map.yaml`](https://github.com/BerriAI/litellm/blob/main/.github/workflows/test-model-map.yaml) |
|
||||
| 2 | Warning log on fallback to local backup | ✅ Done | [`get_model_cost_map.py#L57-L68`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm_core_utils/get_model_cost_map.py#L57-L68) |
|
||||
| 3 | `GetModelCostMap` class with integrity validation helpers | ✅ Done | [`get_model_cost_map.py#L24-L149`](https://github.com/BerriAI/litellm/blob/main/litellm/litellm_core_utils/get_model_cost_map.py#L24-L149) |
|
||||
| 4 | Resilience test suite (bad hosted map, fallback, completion) | ✅ Done | [`test_model_cost_map_resilience.py#L150-L291`](https://github.com/BerriAI/litellm/blob/main/tests/llm_translation/test_model_cost_map_resilience.py#L150-L291) |
|
||||
| 5 | Test that backup model cost map always exists and contains common models | ✅ Done | [`test_model_cost_map_resilience.py#L213-L228`](https://github.com/BerriAI/litellm/blob/main/tests/llm_translation/test_model_cost_map_resilience.py#L213-L228) |
|
||||
|
||||
Enterprises that require zero external dependencies at import time can set `LITELLM_LOCAL_MODEL_COST_MAP=True` to skip the GitHub fetch entirely.
|
||||
|
||||
---
|
||||
|
||||
## Other dependencies on external resources
|
||||
|
||||
| Dependency | Impact if unavailable | Fallback |
|
||||
|---|---|---|
|
||||
| Model cost map (GitHub) | Cost tracking for newer models | Local backup (now with warning) |
|
||||
| JWT public keys (IDP/SSO) | Auth fails | None |
|
||||
| OIDC UserInfo (IDP/SSO) | Auth fails | None |
|
||||
| HuggingFace model API | HF provider calls fail | None |
|
||||
| Ollama tags (localhost) | Ollama model list stale | Static list |
|
||||
|
|
@ -1,6 +1,3 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# MCP OAuth
|
||||
|
||||
LiteLLM supports two OAuth 2.0 flows for MCP servers:
|
||||
|
|
@ -98,8 +95,71 @@ LiteLLM automatically fetches, caches, and refreshes OAuth2 tokens using the `cl
|
|||
|
||||
### Setup
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="config" label="config.yaml">
|
||||
You can configure M2M OAuth via the LiteLLM UI or `config.yaml`.
|
||||
|
||||
### UI Setup
|
||||
|
||||
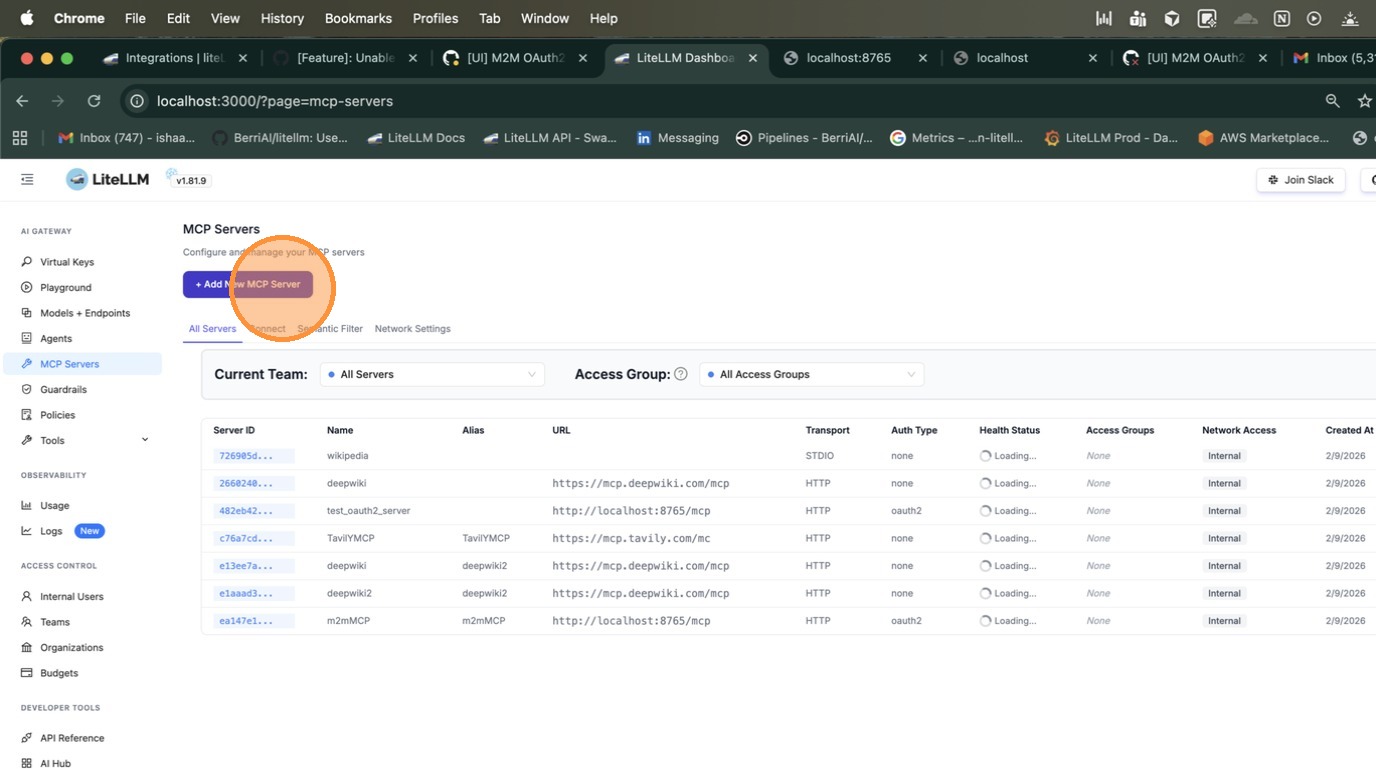
Navigate to the **MCP Servers** page and click **+ Add New MCP Server**.
|
||||
|
||||
|
||||
|
||||
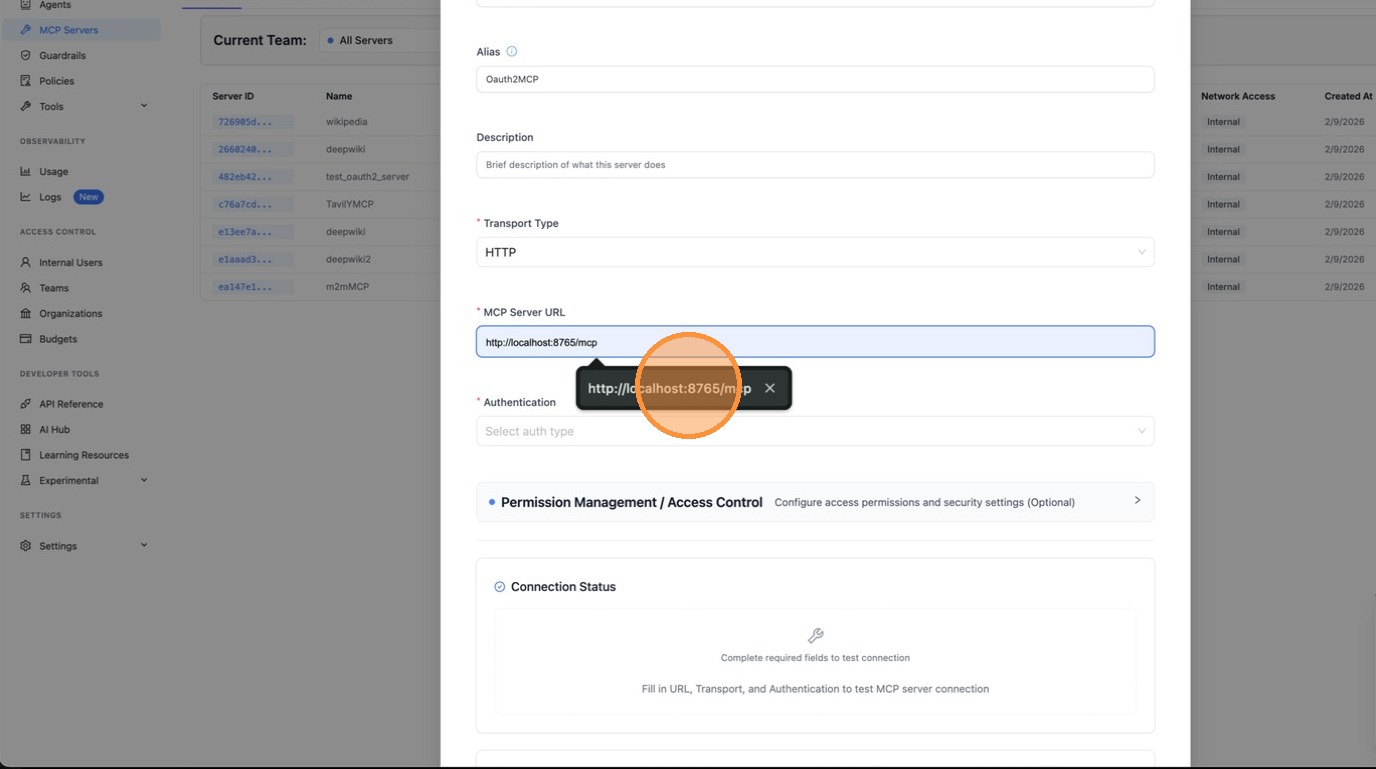
Enter a name for your server and select **HTTP** as the transport type.
|
||||
|
||||
|
||||
|
||||
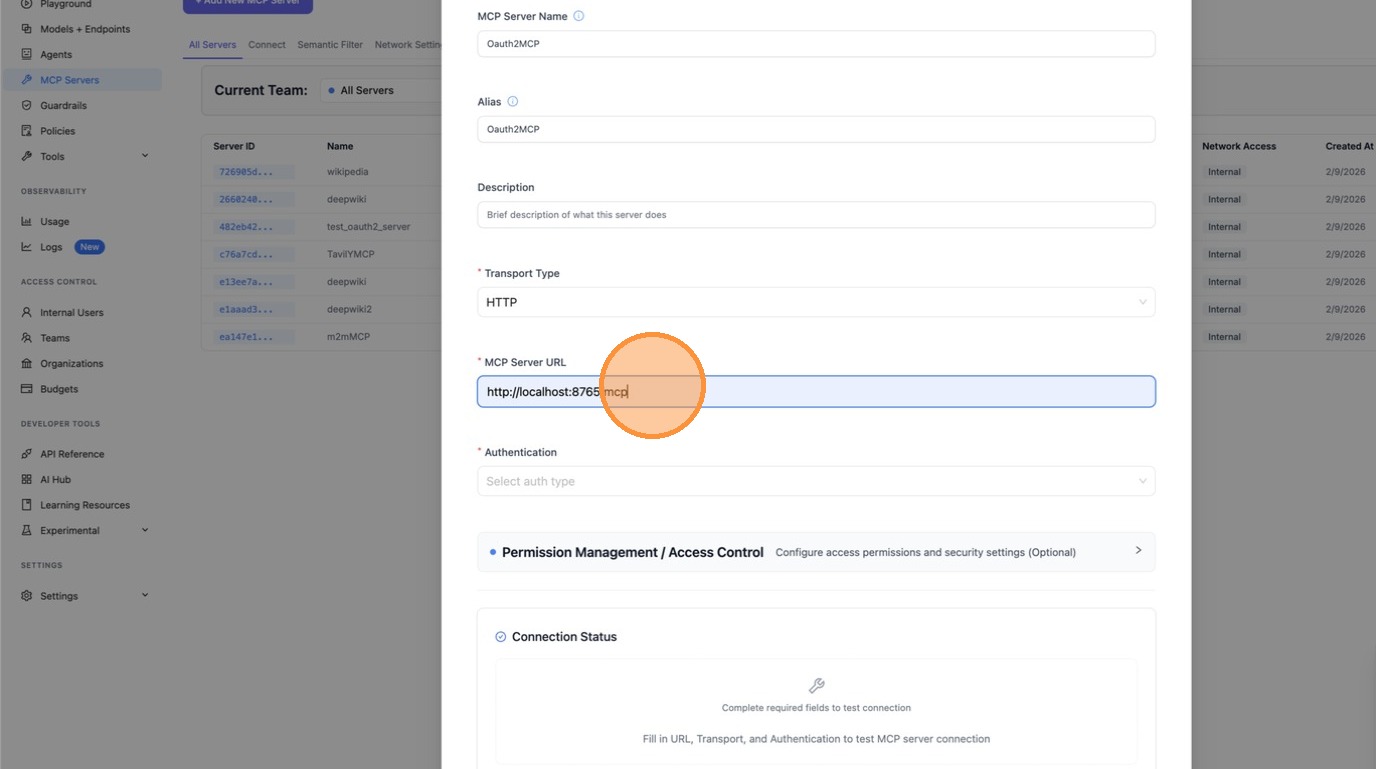
Paste the MCP server URL.
|
||||
|
||||
|
||||
|
||||
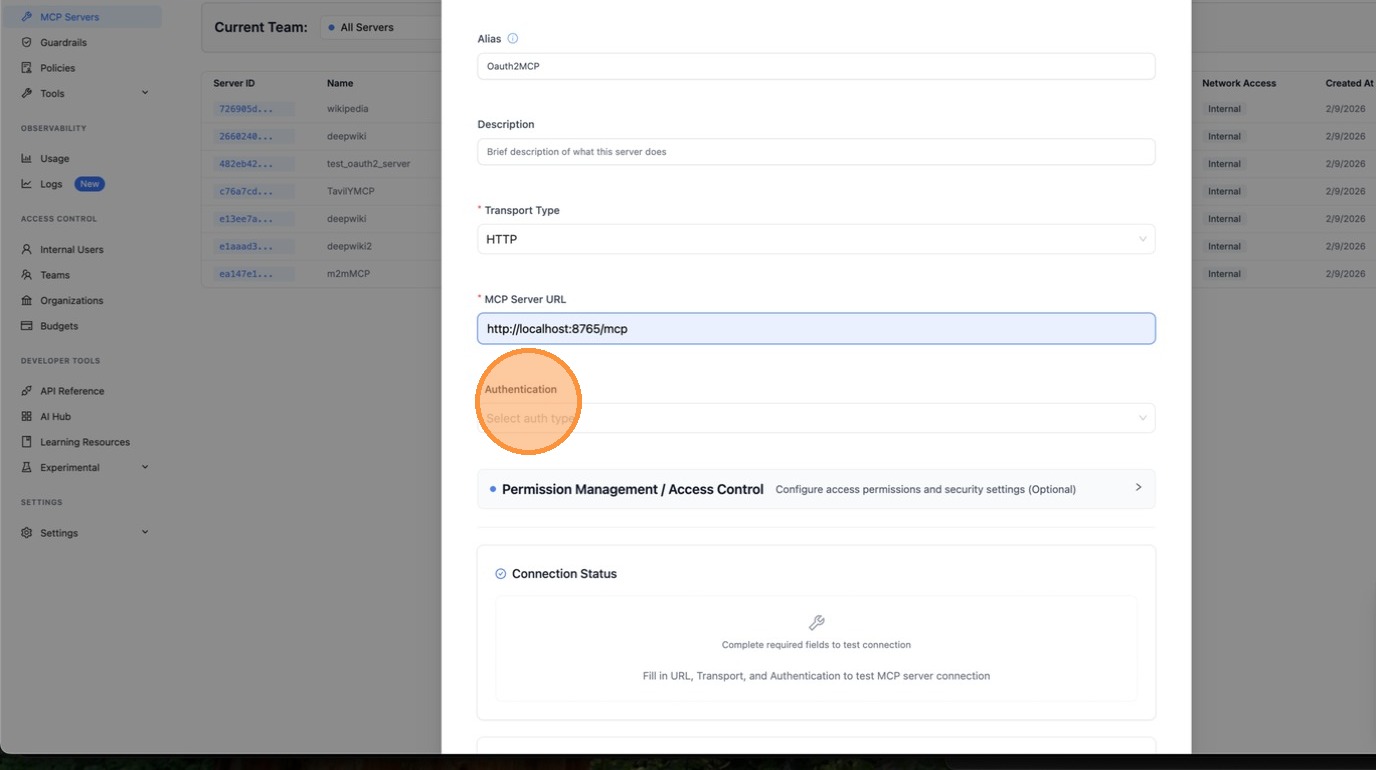
Under **Authentication**, select **OAuth**.
|
||||
|
||||
|
||||
|
||||
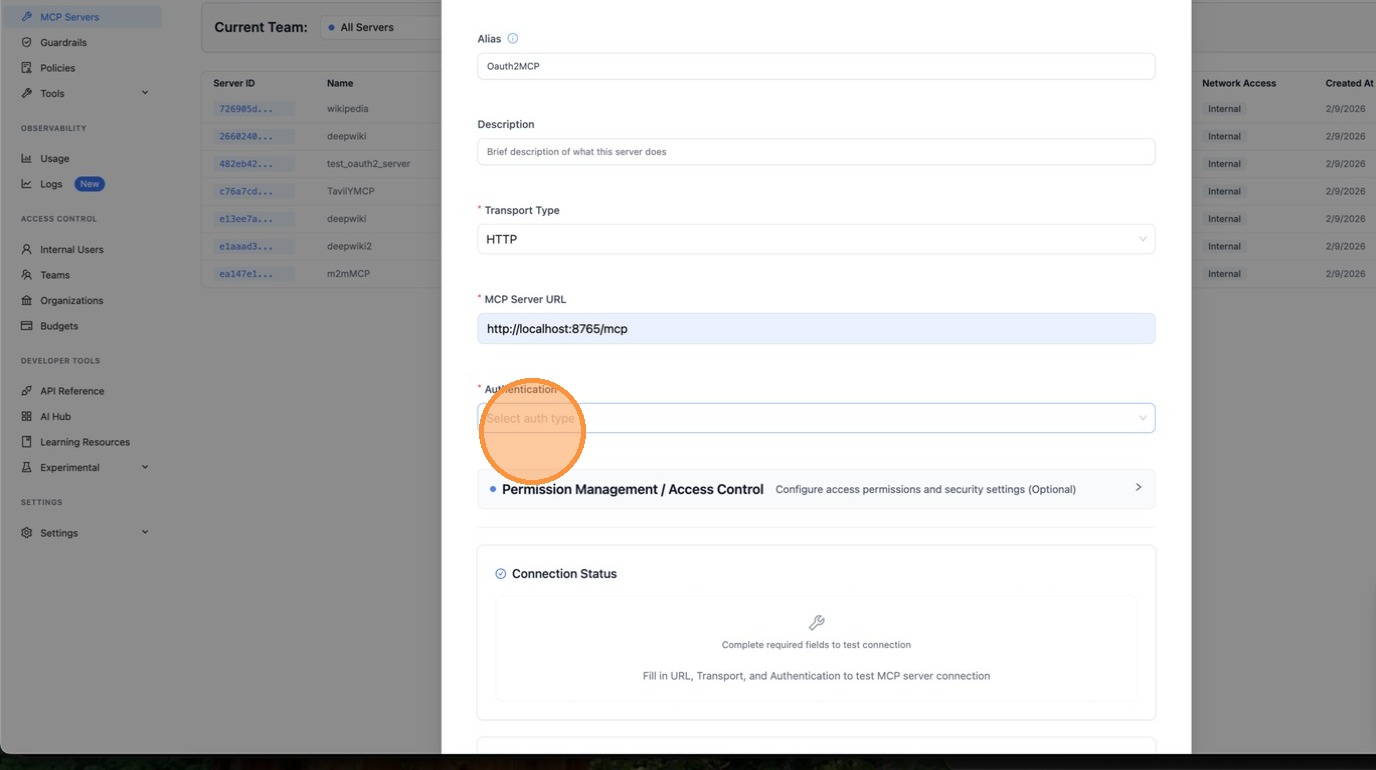
|
||||
|
||||
Choose **Machine-to-Machine (M2M)** as the OAuth flow type. This is for server-to-server authentication using the `client_credentials` grant — no browser interaction required.
|
||||
|
||||
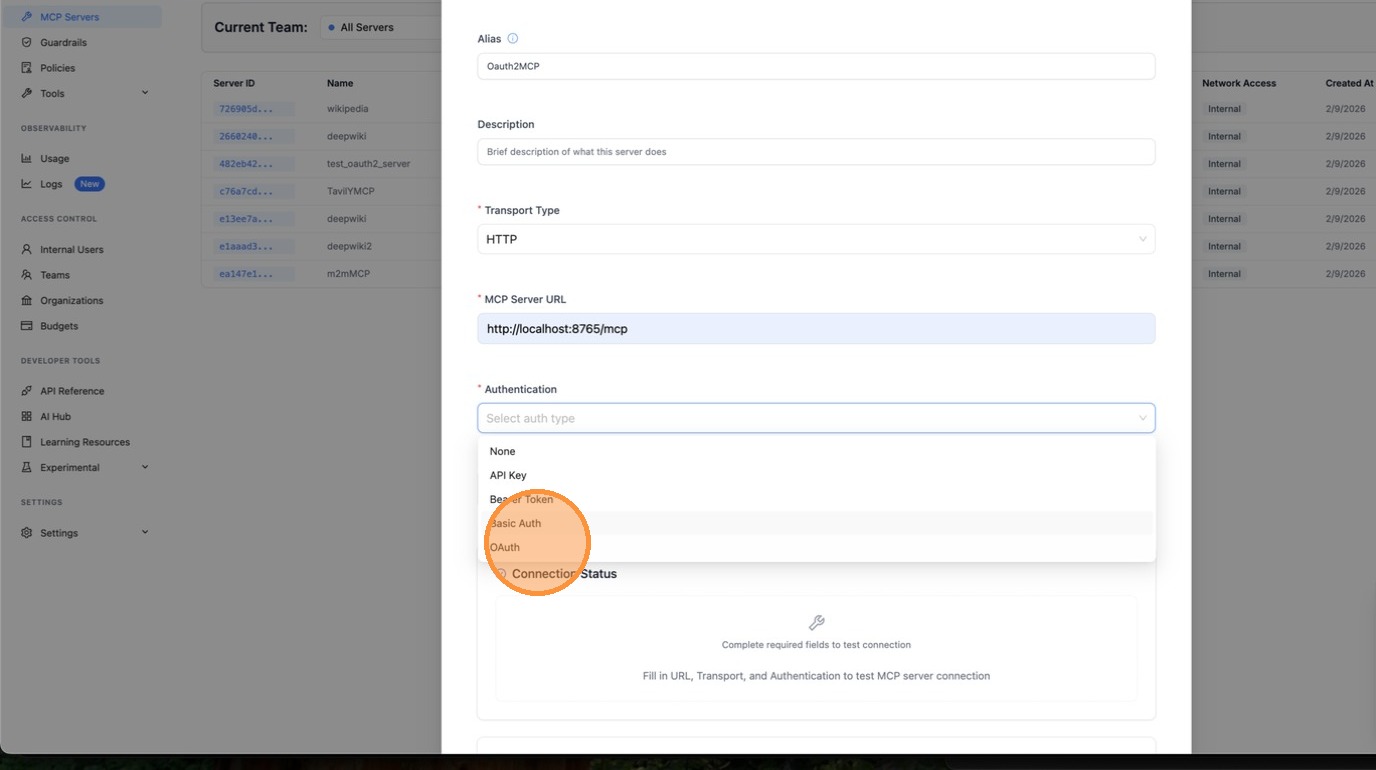
|
||||
|
||||
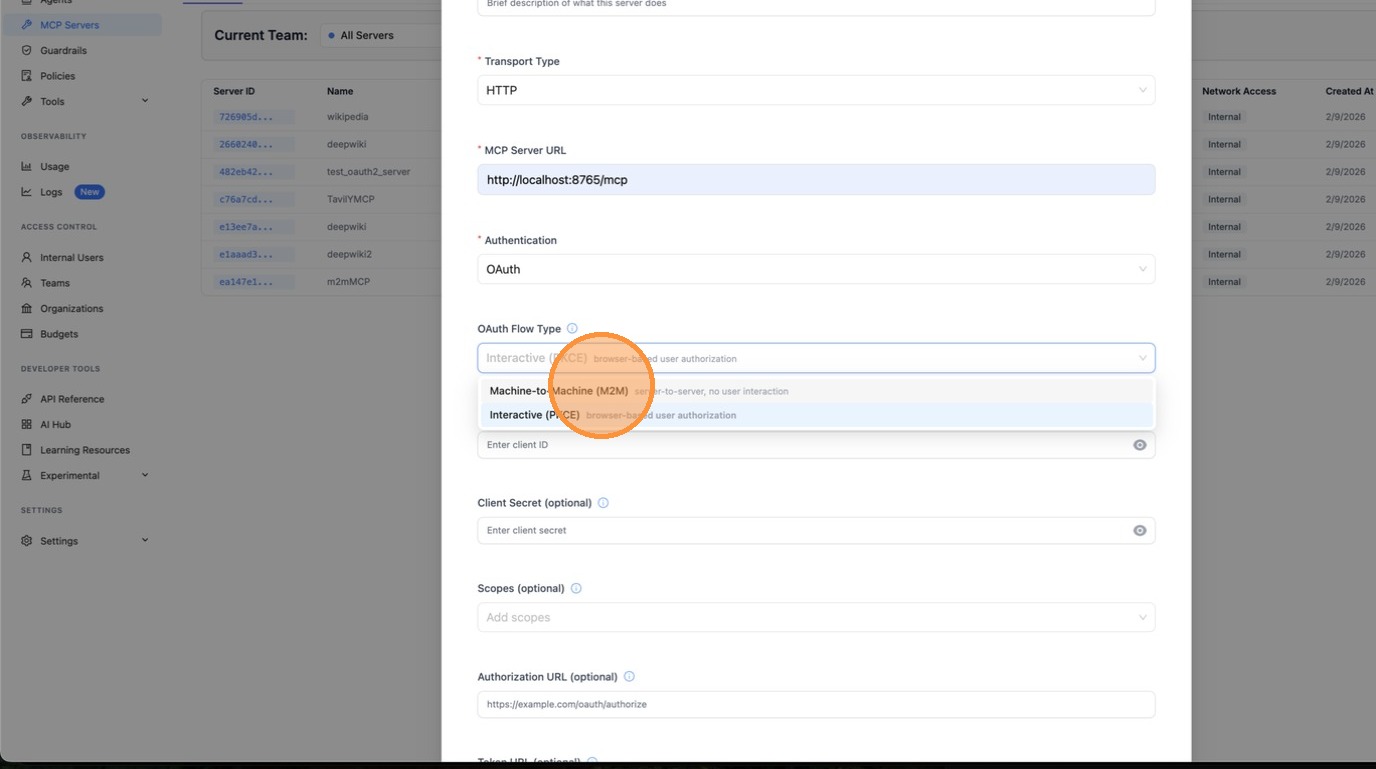
|
||||
|
||||
Fill in the **Client ID** and **Client Secret** provided by your OAuth provider.
|
||||
|
||||
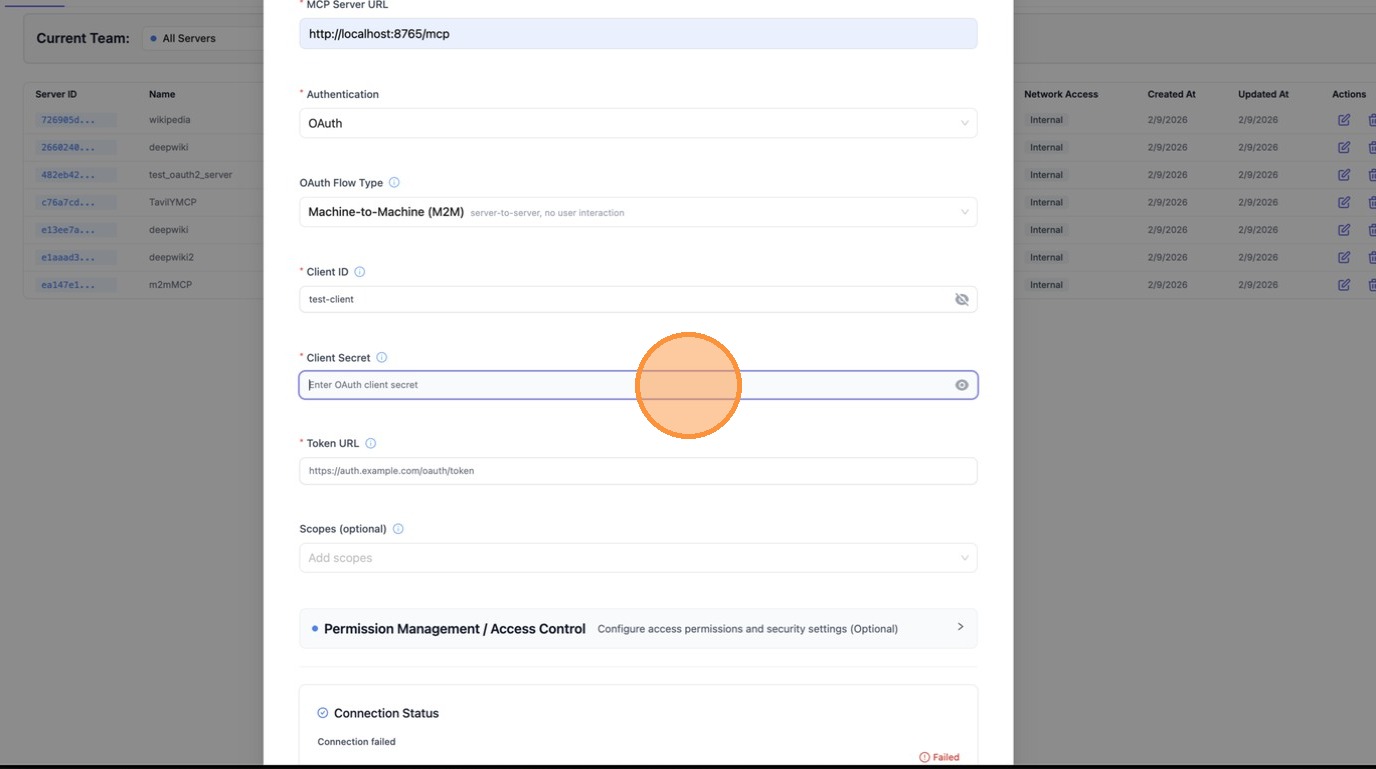
|
||||
|
||||
Enter the **Token URL** — this is the endpoint LiteLLM will call to fetch access tokens using `client_credentials`.
|
||||
|
||||
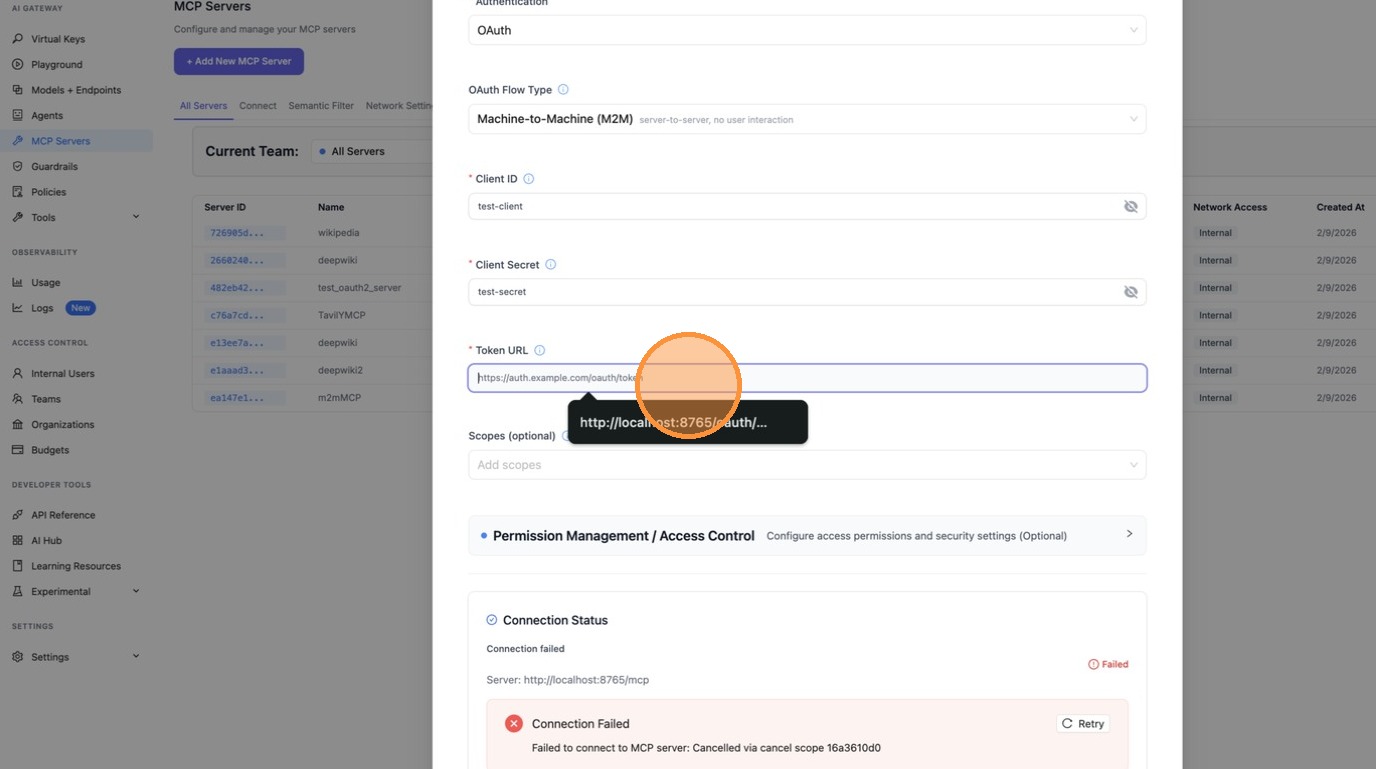
|
||||
|
||||
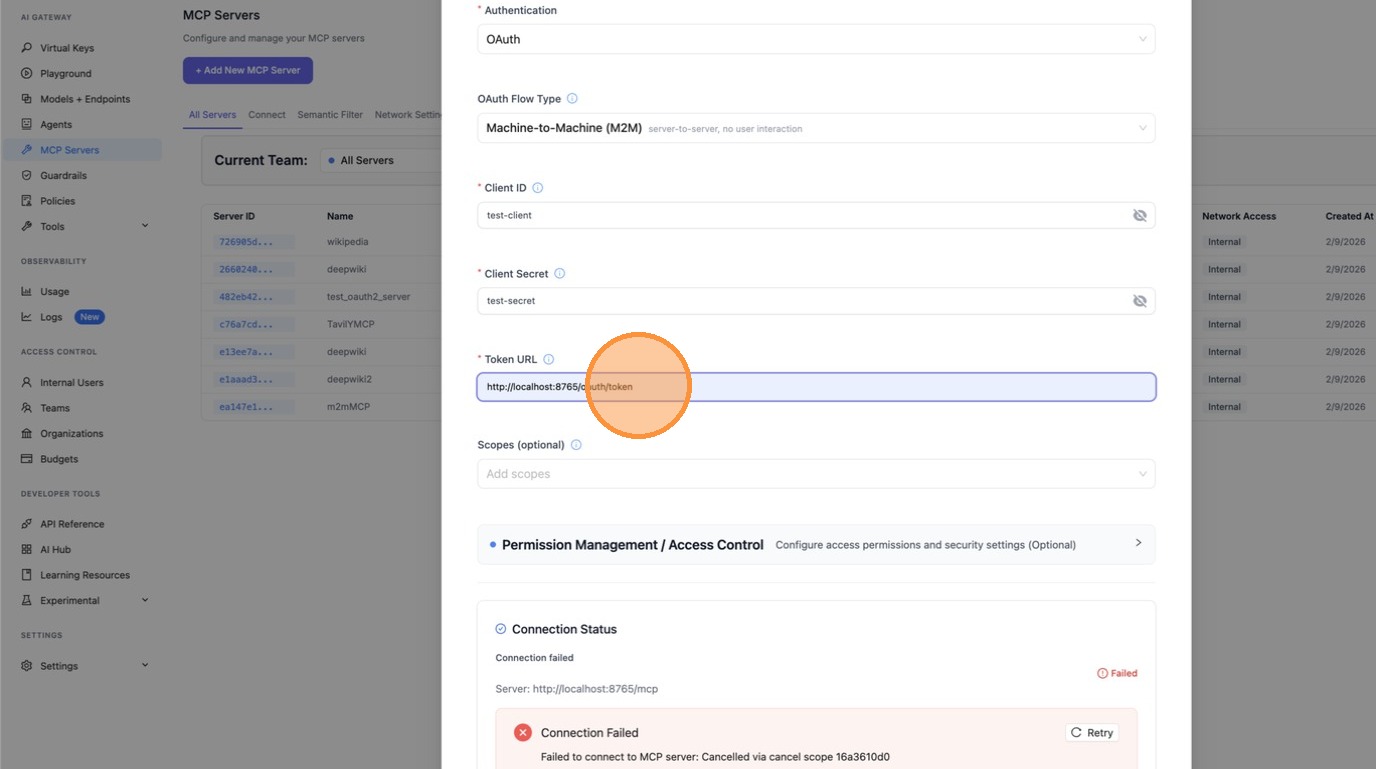
|
||||
|
||||
Scroll down and review the server URL and all fields, then click **Create MCP Server**.
|
||||
|
||||
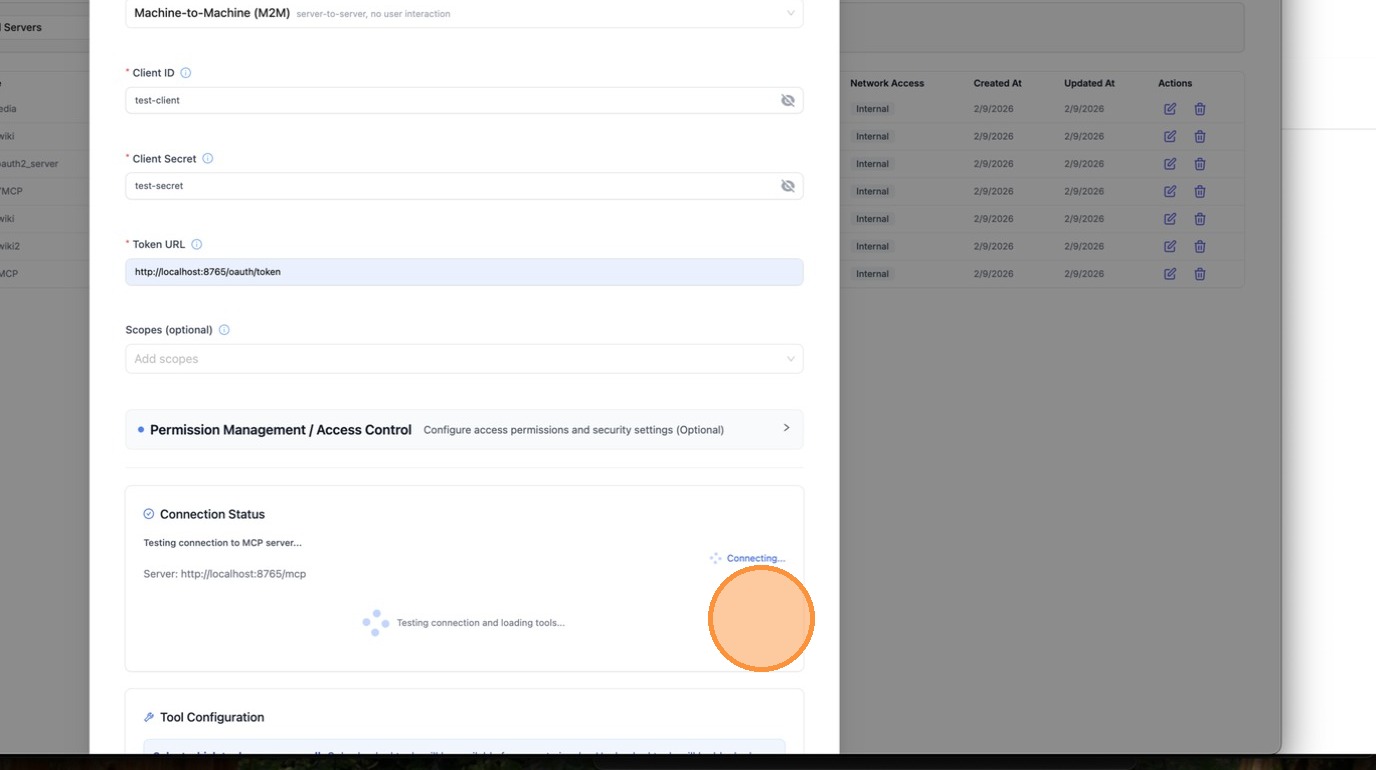
|
||||
|
||||
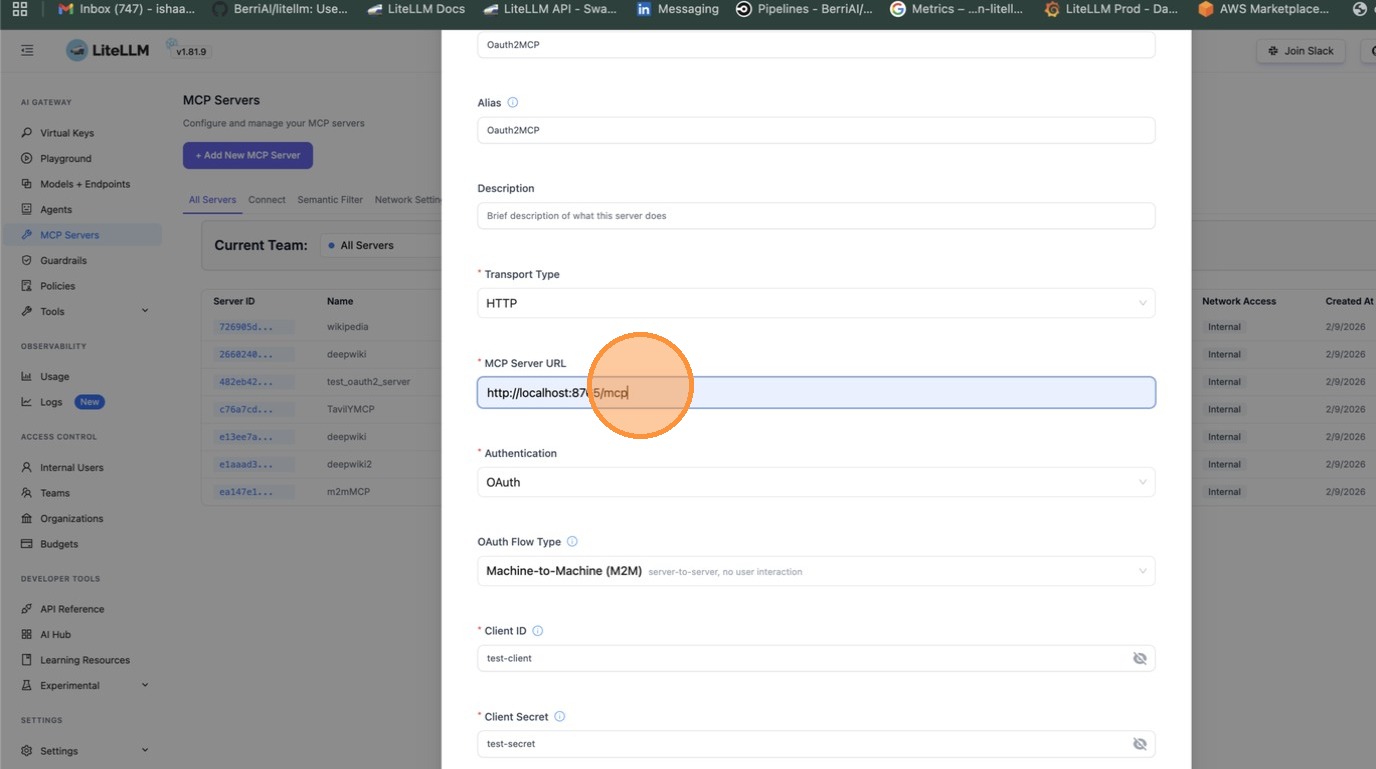
|
||||
|
||||
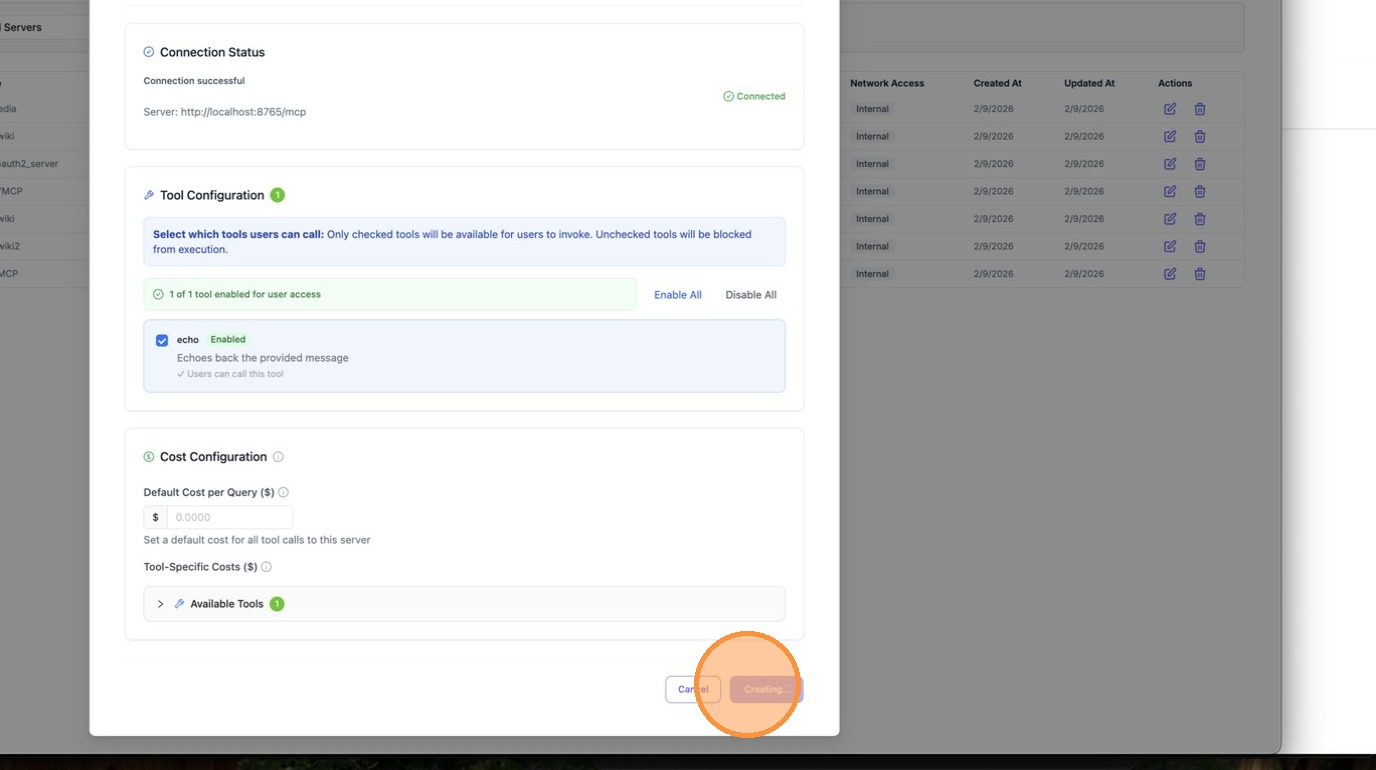
|
||||
|
||||
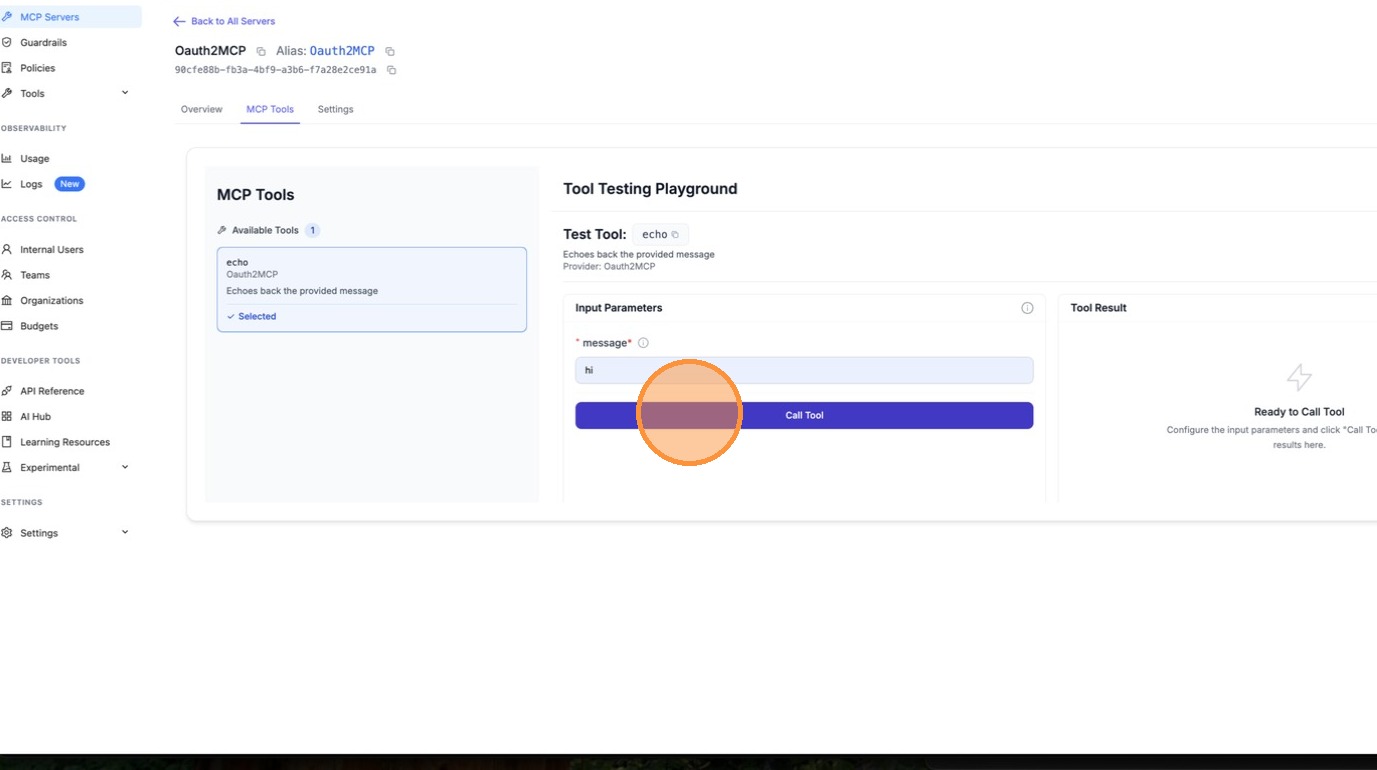
Once created, open the server and navigate to the **MCP Tools** tab to verify that LiteLLM can connect and list available tools.
|
||||
|
||||
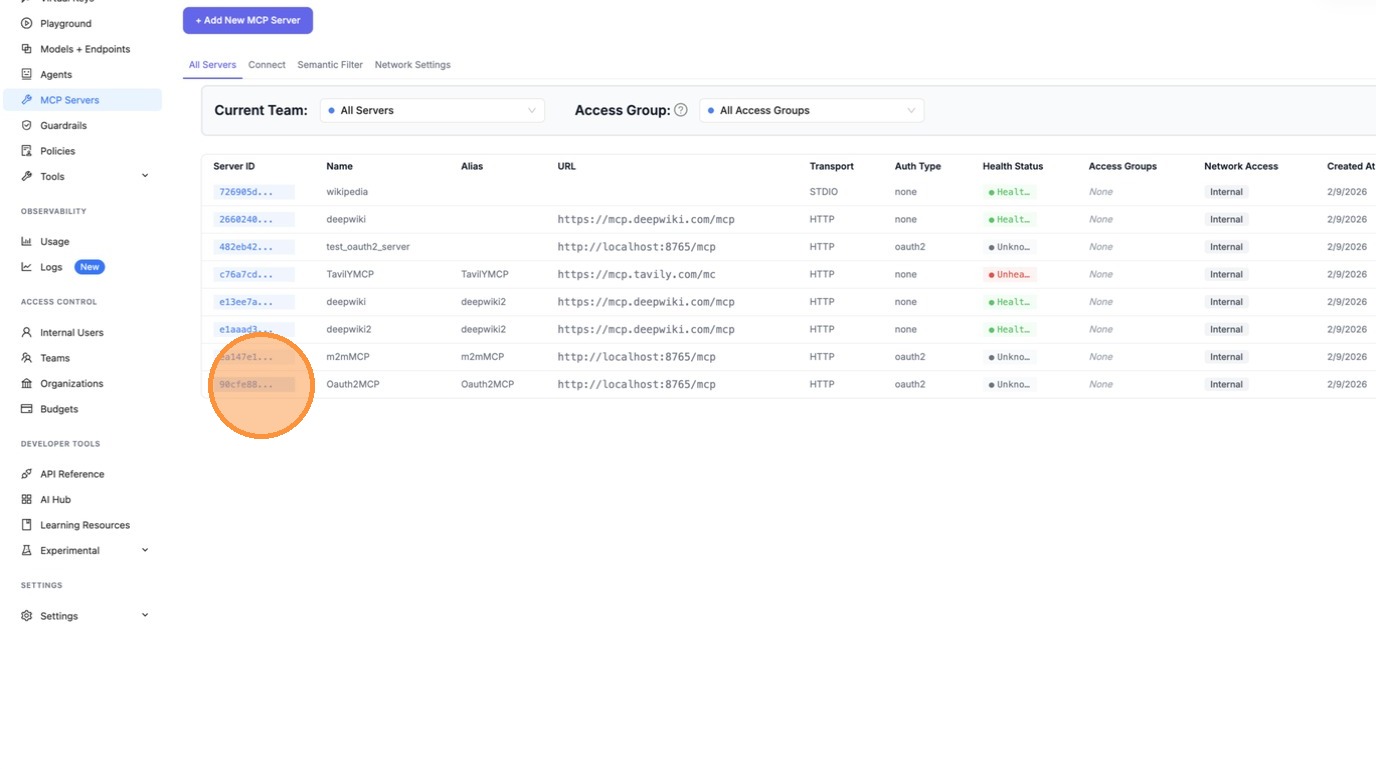
|
||||
|
||||
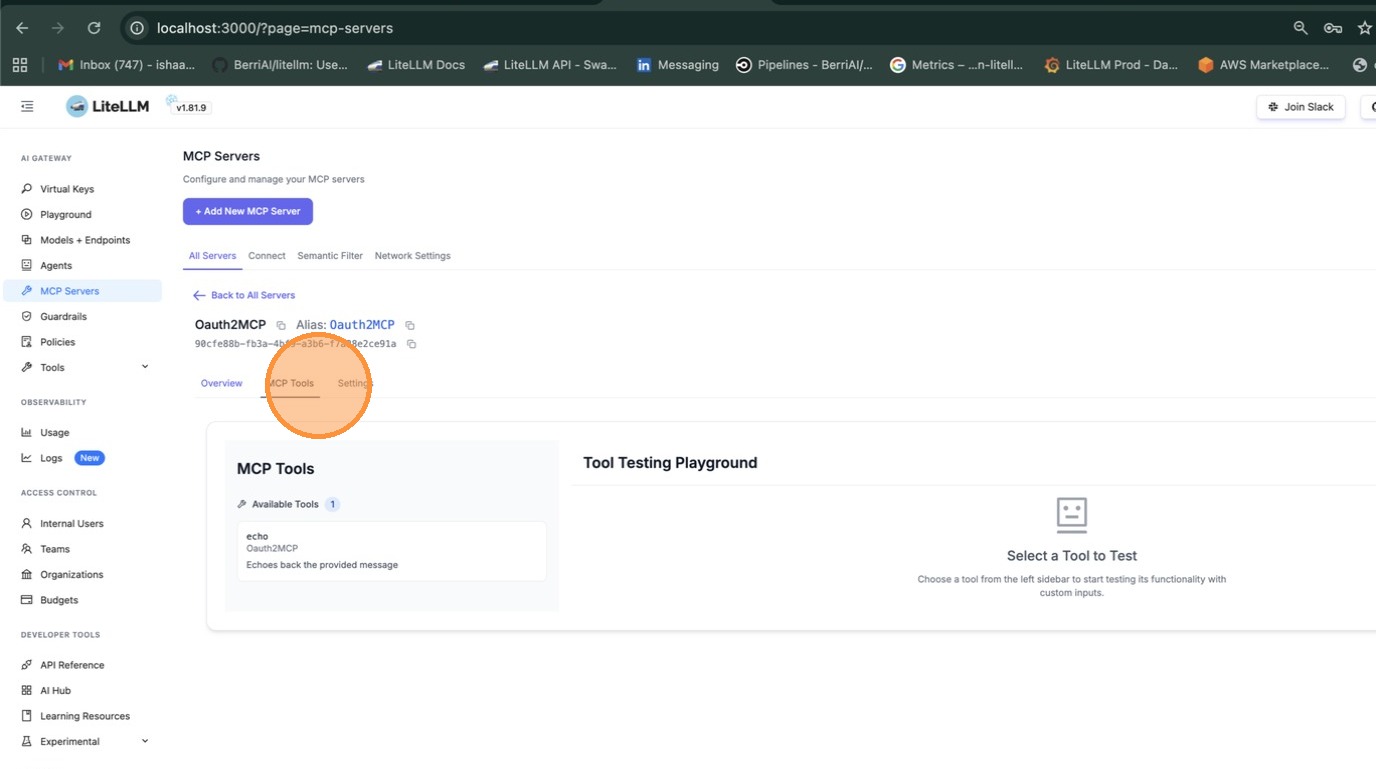
|
||||
|
||||
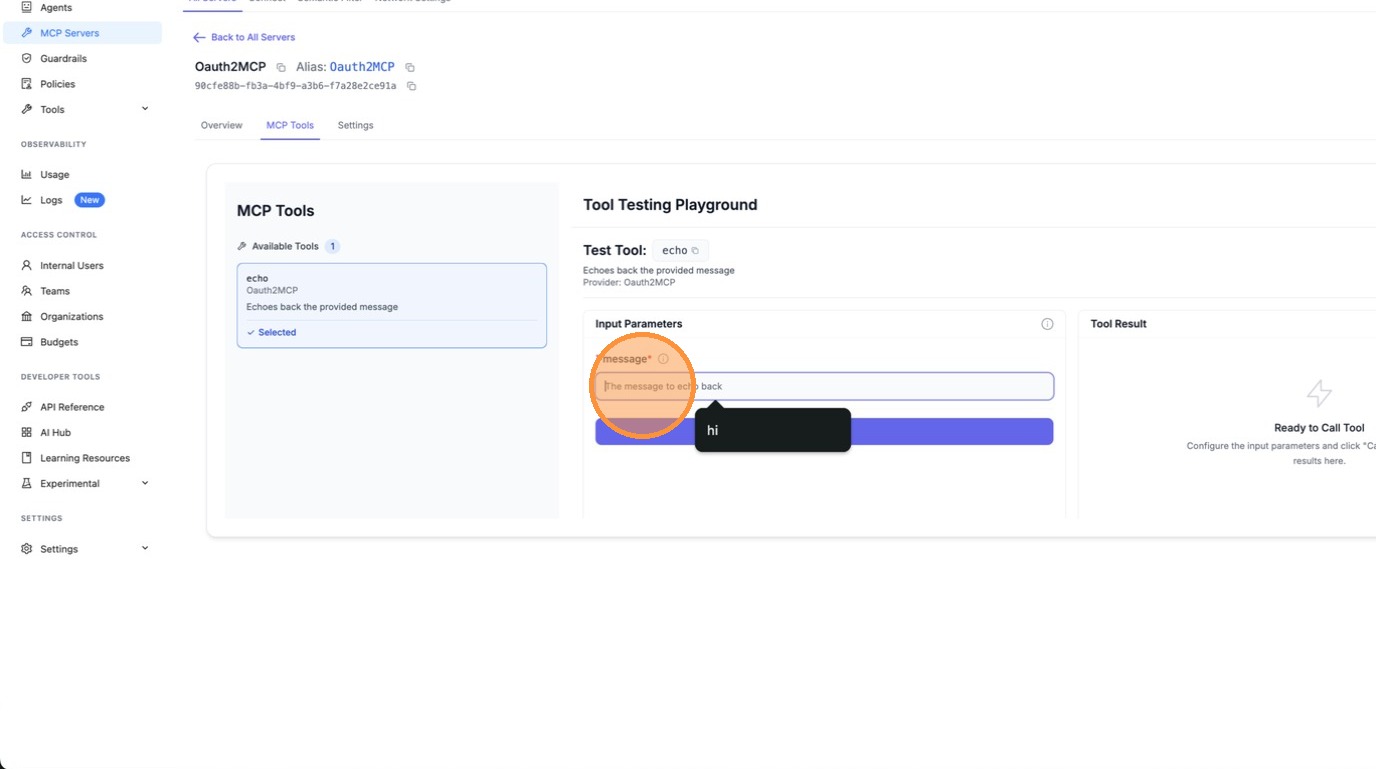
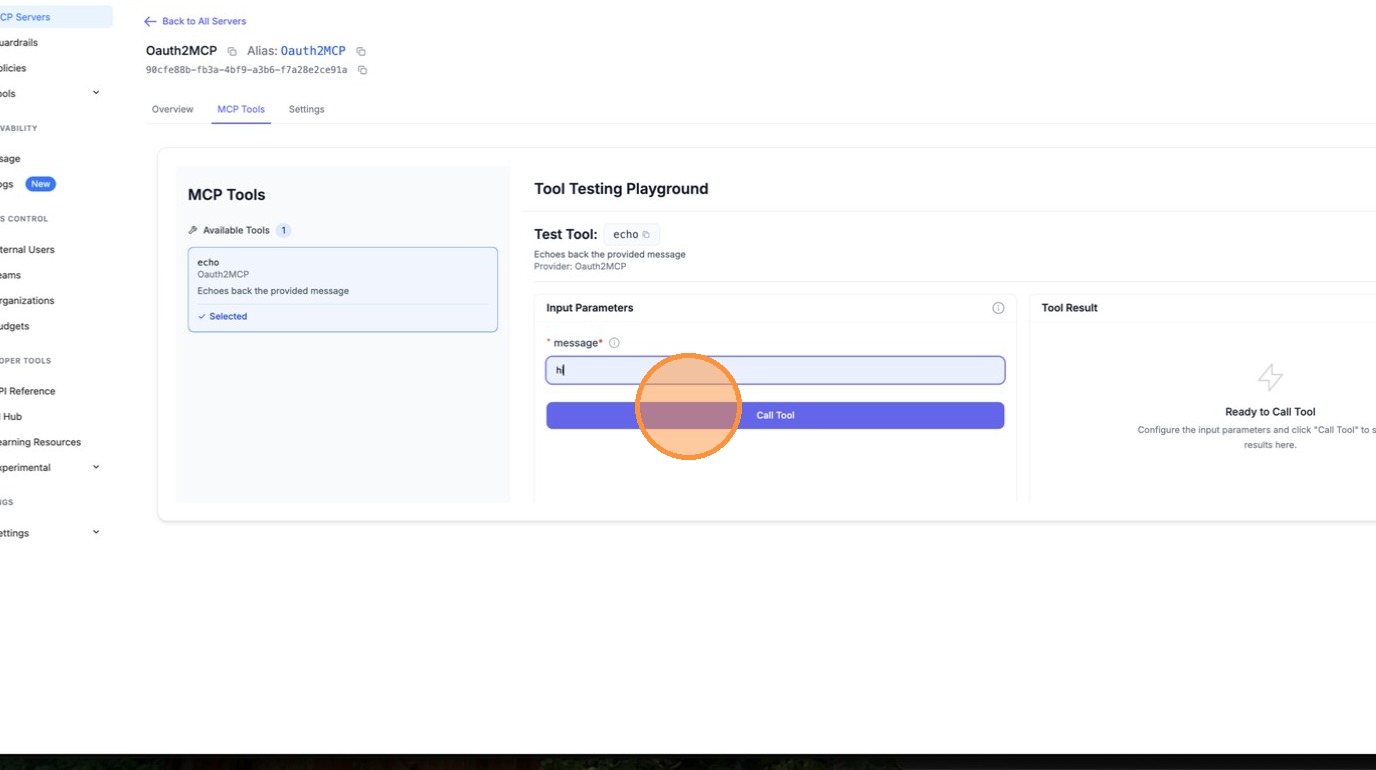
Select a tool (e.g. **echo**) to test it. Fill in the required parameters and click **Call Tool**.
|
||||
|
||||
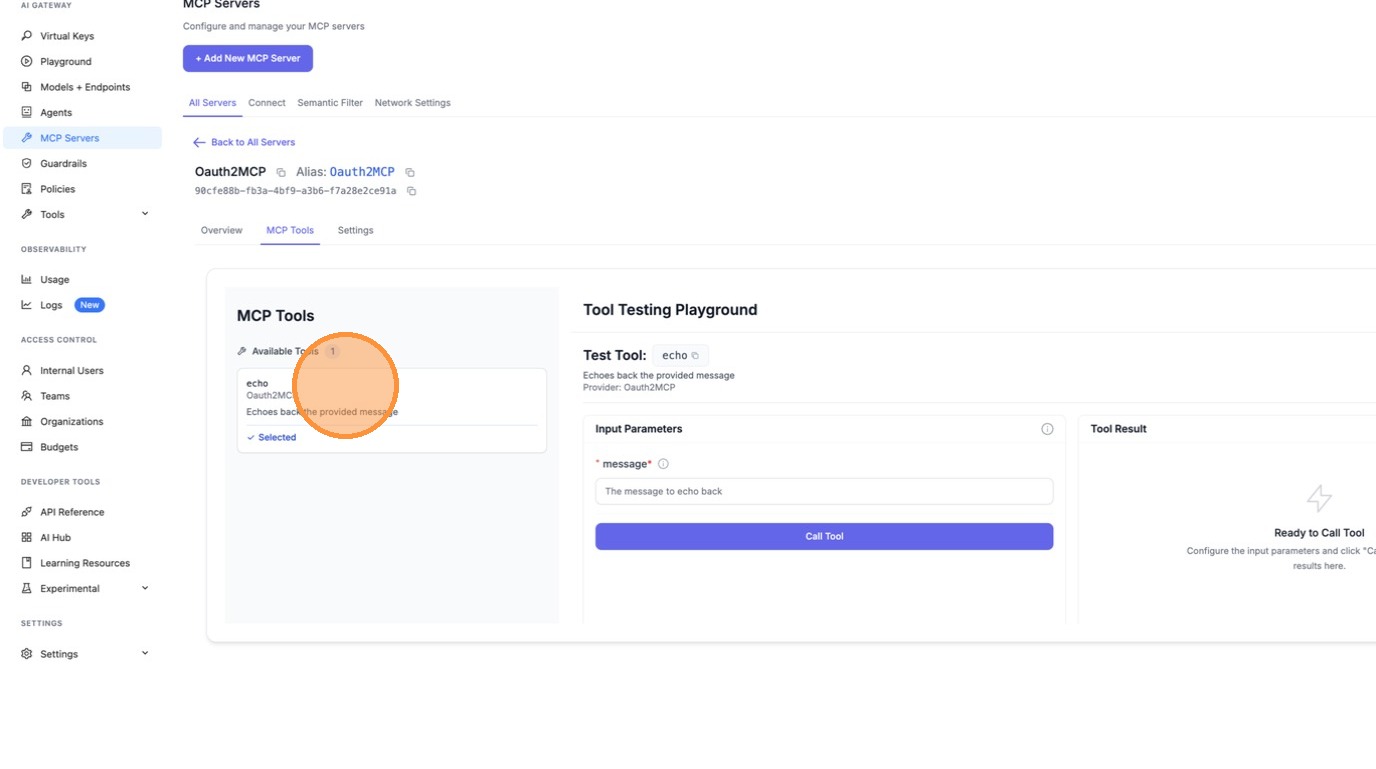
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
LiteLLM automatically fetches an OAuth token behind the scenes and calls the tool. The result confirms the M2M OAuth flow is working end-to-end.
|
||||
|
||||
|
||||
|
||||
### Config.yaml Setup
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
mcp_servers:
|
||||
|
|
@ -112,14 +172,6 @@ mcp_servers:
|
|||
scopes: ["mcp:read", "mcp:write"] # optional
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="ui" label="LiteLLM UI">
|
||||
|
||||
Navigate to **MCP Servers → Add Server → Authentication → OAuth**, then fill in `client_id`, `client_secret`, and `token_url`.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### How It Works
|
||||
|
||||
1. On first MCP request, LiteLLM POSTs to `token_url` with `grant_type=client_credentials`
|
||||
|
|
|
|||
|
|
@ -556,3 +556,147 @@ for event in response.get("completion"):
|
|||
|
||||
print(completion)
|
||||
```
|
||||
|
||||
## Using LangChain AWS SDK with LiteLLM
|
||||
|
||||
You can use the [LangChain AWS SDK](https://python.langchain.com/docs/integrations/chat/bedrock/) with LiteLLM Proxy to get cost tracking, load balancing, and other LiteLLM features.
|
||||
|
||||
### Quick Start
|
||||
|
||||
**1. Install LangChain AWS**:
|
||||
|
||||
```bash showLineNumbers
|
||||
pip install langchain-aws
|
||||
```
|
||||
|
||||
**2. Setup LiteLLM Proxy**:
|
||||
|
||||
Create a `config.yaml`:
|
||||
|
||||
```yaml showLineNumbers
|
||||
model_list:
|
||||
- model_name: claude-sonnet
|
||||
litellm_params:
|
||||
model: bedrock/us.anthropic.claude-3-7-sonnet-20250219-v1:0
|
||||
aws_region_name: us-east-1
|
||||
custom_llm_provider: bedrock
|
||||
```
|
||||
|
||||
Start the proxy:
|
||||
|
||||
```bash showLineNumbers
|
||||
export AWS_ACCESS_KEY_ID="your-access-key"
|
||||
export AWS_SECRET_ACCESS_KEY="your-secret-key"
|
||||
|
||||
litellm --config config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
**3. Use LangChain with LiteLLM**:
|
||||
|
||||
```python showLineNumbers
|
||||
from langchain_aws import ChatBedrockConverse
|
||||
from langchain_core.messages import HumanMessage
|
||||
|
||||
# Your LiteLLM API key
|
||||
API_KEY = "Bearer sk-1234"
|
||||
|
||||
# Initialize ChatBedrockConverse pointing to LiteLLM proxy
|
||||
llm = ChatBedrockConverse(
|
||||
model_id="us.anthropic.claude-3-7-sonnet-20250219-v1:0",
|
||||
endpoint_url="http://localhost:4000/bedrock",
|
||||
region_name="us-east-1",
|
||||
aws_access_key_id=API_KEY,
|
||||
aws_secret_access_key="bedrock" # Any non-empty value works
|
||||
)
|
||||
|
||||
# Invoke the model
|
||||
messages = [HumanMessage(content="Hello, how are you?")]
|
||||
response = llm.invoke(messages)
|
||||
|
||||
print(response.content)
|
||||
```
|
||||
|
||||
### Advanced Example: PDF Document Processing with Citations
|
||||
|
||||
LangChain AWS SDK supports Bedrock's document processing features. Here's how to use it with LiteLLM:
|
||||
|
||||
```python showLineNumbers
|
||||
import os
|
||||
import json
|
||||
from langchain_aws import ChatBedrockConverse
|
||||
from langchain_core.messages import HumanMessage
|
||||
|
||||
# Your LiteLLM API key
|
||||
API_KEY = "Bearer sk-1234"
|
||||
|
||||
def get_llm() -> ChatBedrockConverse:
|
||||
"""Initialize LLM pointing to LiteLLM proxy"""
|
||||
llm = ChatBedrockConverse(
|
||||
model_id="us.anthropic.claude-3-7-sonnet-20250219-v1:0",
|
||||
base_model_id="anthropic.claude-3-7-sonnet-20250219-v1:0",
|
||||
endpoint_url="http://localhost:4000/bedrock",
|
||||
region_name="us-east-1",
|
||||
aws_access_key_id=API_KEY,
|
||||
aws_secret_access_key="bedrock"
|
||||
)
|
||||
return llm
|
||||
|
||||
if __name__ == "__main__":
|
||||
# Initialize the LLM
|
||||
llm = get_llm()
|
||||
|
||||
# Read PDF file as bytes (Converse API requires raw bytes)
|
||||
with open("your-document.pdf", "rb") as file:
|
||||
file_bytes = file.read()
|
||||
|
||||
# Prepare messages with document attachment
|
||||
messages = [
|
||||
HumanMessage(content=[
|
||||
{"text": "What is the policy number in this document?"},
|
||||
{
|
||||
"document": {
|
||||
"format": "pdf",
|
||||
"name": "PolicyDocument",
|
||||
"source": {"bytes": file_bytes},
|
||||
"citations": {"enabled": True}
|
||||
}
|
||||
}
|
||||
])
|
||||
]
|
||||
|
||||
# Invoke the LLM
|
||||
response = llm.invoke(messages)
|
||||
|
||||
# Print response with citations
|
||||
print(json.dumps(response.content, indent=4))
|
||||
```
|
||||
|
||||
### Supported LangChain Features
|
||||
|
||||
All LangChain AWS features work with LiteLLM:
|
||||
|
||||
| Feature | Supported | Notes |
|
||||
|---------|-----------|-------|
|
||||
| Text Generation | ✅ | Full support |
|
||||
| Streaming | ✅ | Use `stream()` method |
|
||||
| Document Processing | ✅ | PDF, images, etc. |
|
||||
| Citations | ✅ | Enable in document config |
|
||||
| Tool Use | ✅ | Function calling support |
|
||||
| Multi-modal | ✅ | Text + images + documents |
|
||||
|
||||
### Troubleshooting
|
||||
|
||||
**Issue**: `UnknownOperationException` error
|
||||
|
||||
**Solution**: Make sure you're using the correct endpoint URL format:
|
||||
- ✅ Correct: `http://localhost:4000/bedrock`
|
||||
- ❌ Wrong: `http://localhost:4000/bedrock/v2`
|
||||
|
||||
**Issue**: Authentication errors
|
||||
|
||||
**Solution**: Ensure your API key is in the correct format:
|
||||
```python
|
||||
aws_access_key_id="Bearer sk-1234" # Include "Bearer " prefix
|
||||
```
|
||||
|
|
|
|||
|
|
@ -120,6 +120,293 @@ All models listed here https://docs.perplexity.ai/docs/model-cards are supported
|
|||
|
||||
|
||||
|
||||
## Agentic Research API (Responses API)
|
||||
|
||||
Requires v1.72.6+
|
||||
|
||||
|
||||
### Using Presets
|
||||
|
||||
Presets provide optimized defaults for specific use cases. Start with a preset for quick setup:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
# Using the pro-search preset
|
||||
response = responses(
|
||||
model="perplexity/preset/pro-search",
|
||||
input="What are the latest developments in AI?",
|
||||
custom_llm_provider="perplexity",
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="Proxy">
|
||||
|
||||
1. Setup config.yaml
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: perplexity-pro-search
|
||||
litellm_params:
|
||||
model: perplexity/preset/pro-search
|
||||
api_key: os.environ/PERPLEXITY_API_KEY
|
||||
```
|
||||
|
||||
2. Start proxy
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
3. Test it!
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/responses \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer anything" \
|
||||
-d '{
|
||||
"model": "perplexity-pro-search",
|
||||
"input": "What are the latest developments in AI?"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Using Third-Party Models
|
||||
|
||||
Access models from OpenAI, Anthropic, Google, xAI, and other providers through Perplexity's unified API:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="openai" label="OpenAI">
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/openai/gpt-4o",
|
||||
input="Explain quantum computing in simple terms",
|
||||
custom_llm_provider="perplexity",
|
||||
max_output_tokens=500,
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="anthropic" label="Anthropic">
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/anthropic/claude-3-5-sonnet-20241022",
|
||||
input="Write a short story about a robot learning to paint",
|
||||
custom_llm_provider="perplexity",
|
||||
max_output_tokens=500,
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="google" label="Google">
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/google/gemini-2.0-flash-exp",
|
||||
input="Explain the concept of neural networks",
|
||||
custom_llm_provider="perplexity",
|
||||
max_output_tokens=500,
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="xai" label="xAI">
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/xai/grok-2-1212",
|
||||
input="What makes a good AI assistant?",
|
||||
custom_llm_provider="perplexity",
|
||||
max_output_tokens=500,
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Web Search Tool
|
||||
|
||||
Enable web search capabilities to access real-time information:
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/openai/gpt-4o",
|
||||
input="What's the weather in San Francisco today?",
|
||||
custom_llm_provider="perplexity",
|
||||
tools=[{"type": "web_search"}],
|
||||
instructions="You have access to a web_search tool. Use it for questions about current events.",
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
|
||||
### Reasoning Effort (Responses API)
|
||||
|
||||
Control the reasoning effort level for reasoning-capable models:
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/openai/gpt-5.2",
|
||||
input="Solve this complex problem step by step",
|
||||
custom_llm_provider="perplexity",
|
||||
reasoning={"effort": "high"}, # Options: low, medium, high
|
||||
max_output_tokens=1000,
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
### Multi-Turn Conversations
|
||||
|
||||
Use message arrays for multi-turn conversations with context:
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/anthropic/claude-3-5-sonnet-20241022",
|
||||
input=[
|
||||
{"type": "message", "role": "system", "content": "You are a helpful assistant."},
|
||||
{"type": "message", "role": "user", "content": "What are the latest AI developments?"},
|
||||
],
|
||||
custom_llm_provider="perplexity",
|
||||
instructions="Provide detailed, well-researched answers.",
|
||||
max_output_tokens=800,
|
||||
)
|
||||
|
||||
print(response.output)
|
||||
```
|
||||
|
||||
### Streaming Responses
|
||||
|
||||
Stream responses for real-time output:
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
response = responses(
|
||||
model="perplexity/openai/gpt-4o",
|
||||
input="Tell me a story about space exploration",
|
||||
custom_llm_provider="perplexity",
|
||||
stream=True,
|
||||
max_output_tokens=500,
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
if hasattr(chunk, 'type'):
|
||||
if chunk.type == "response.output_text.delta":
|
||||
print(chunk.delta, end="", flush=True)
|
||||
```
|
||||
|
||||
### Supported Third-Party Models
|
||||
|
||||
| Provider | Model Name | Function Call |
|
||||
|----------|------------|---------------|
|
||||
| OpenAI | gpt-4o | `responses(model="perplexity/openai/gpt-4o", ...)` |
|
||||
| OpenAI | gpt-4o-mini | `responses(model="perplexity/openai/gpt-4o-mini", ...)` |
|
||||
| OpenAI | gpt-5.2 | `responses(model="perplexity/openai/gpt-5.2", ...)` |
|
||||
| Anthropic | claude-3-5-sonnet-20241022 | `responses(model="perplexity/anthropic/claude-3-5-sonnet-20241022", ...)` |
|
||||
| Anthropic | claude-3-5-haiku-20241022 | `responses(model="perplexity/anthropic/claude-3-5-haiku-20241022", ...)` |
|
||||
| Google | gemini-2.0-flash-exp | `responses(model="perplexity/google/gemini-2.0-flash-exp", ...)` |
|
||||
| Google | gemini-2.0-flash-thinking-exp | `responses(model="perplexity/google/gemini-2.0-flash-thinking-exp", ...)` |
|
||||
| xAI | grok-2-1212 | `responses(model="perplexity/xai/grok-2-1212", ...)` |
|
||||
| xAI | grok-2-vision-1212 | `responses(model="perplexity/xai/grok-2-vision-1212", ...)` |
|
||||
|
||||
### Available Presets
|
||||
|
||||
| Preset Name | Function Call |
|
||||
|----------------|--------------------------------------------------------|
|
||||
| fast-search | `responses(model="perplexity/preset/fast-search", ...)`|
|
||||
| pro-search | `responses(model="perplexity/preset/pro-search", ...)` |
|
||||
| deep-research | `responses(model="perplexity/preset/deep-research", ...)`|
|
||||
|
||||
### Complete Example
|
||||
|
||||
```python
|
||||
from litellm import responses
|
||||
import os
|
||||
|
||||
os.environ['PERPLEXITY_API_KEY'] = ""
|
||||
|
||||
# Comprehensive example with multiple features
|
||||
response = responses(
|
||||
model="perplexity/openai/gpt-4o",
|
||||
input="Research the latest developments in quantum computing and provide sources",
|
||||
custom_llm_provider="perplexity",
|
||||
tools=[
|
||||
{"type": "web_search"},
|
||||
{"type": "fetch_url"}
|
||||
],
|
||||
instructions="Use web_search to find relevant information and fetch_url to retrieve detailed content from sources. Provide citations for all claims.",
|
||||
max_output_tokens=1000,
|
||||
temperature=0.7,
|
||||
)
|
||||
|
||||
print(f"Response ID: {response.id}")
|
||||
print(f"Model: {response.model}")
|
||||
print(f"Status: {response.status}")
|
||||
print(f"Output: {response.output}")
|
||||
print(f"Usage: {response.usage}")
|
||||
```
|
||||
|
||||
:::info
|
||||
|
||||
For more information about passing provider-specific parameters, [go here](../completion/provider_specific_params.md)
|
||||
|
|
|
|||
|
|
@ -223,6 +223,7 @@ GENERIC_USER_FIRST_NAME_ATTRIBUTE = "first_name"
|
|||
GENERIC_USER_LAST_NAME_ATTRIBUTE = "last_name"
|
||||
GENERIC_USER_ROLE_ATTRIBUTE = "given_role"
|
||||
GENERIC_USER_PROVIDER_ATTRIBUTE = "provider"
|
||||
GENERIC_USER_EXTRA_ATTRIBUTES = "department,employee_id,manager" # comma-separated list of additional fields to extract from SSO response
|
||||
GENERIC_CLIENT_STATE = "some-state" # if the provider needs a state parameter
|
||||
GENERIC_INCLUDE_CLIENT_ID = "false" # some providers enforce that the client_id is not in the body
|
||||
GENERIC_SCOPE = "openid profile email" # default scope openid is sometimes not enough to retrieve basic user info like first_name and last_name located in profile scope
|
||||
|
|
@ -239,6 +240,40 @@ Use `GENERIC_USER_ROLE_ATTRIBUTE` to specify which attribute in the SSO token co
|
|||
|
||||
Nested attribute paths are supported (e.g., `claims.role` or `attributes.litellm_role`).
|
||||
|
||||
**Capturing Additional SSO Fields**
|
||||
|
||||
Use `GENERIC_USER_EXTRA_ATTRIBUTES` to extract additional fields from the SSO provider response beyond the standard user attributes (id, email, name, etc.). This is useful when you need to access custom organization-specific data (e.g., department, employee ID, groups) in your [custom SSO handler](./custom_sso.md).
|
||||
|
||||
```shell
|
||||
# Comma-separated list of field names to extract
|
||||
GENERIC_USER_EXTRA_ATTRIBUTES="department,employee_id,manager,groups"
|
||||
```
|
||||
|
||||
**Accessing Extra Fields in Custom SSO Handler:**
|
||||
|
||||
```python
|
||||
from litellm.proxy.management_endpoints.types import CustomOpenID
|
||||
|
||||
async def custom_sso_handler(userIDPInfo: CustomOpenID):
|
||||
# Access the extra fields
|
||||
extra_fields = getattr(userIDPInfo, 'extra_fields', None) or {}
|
||||
|
||||
user_department = extra_fields.get("department")
|
||||
employee_id = extra_fields.get("employee_id")
|
||||
user_groups = extra_fields.get("groups", [])
|
||||
|
||||
# Use these fields for custom logic (e.g., team assignment, access control)
|
||||
# ...
|
||||
```
|
||||
|
||||
**Nested Field Paths:**
|
||||
|
||||
Dot notation is supported for nested fields:
|
||||
|
||||
```shell
|
||||
GENERIC_USER_EXTRA_ATTRIBUTES="org_info.department,org_info.cost_center,metadata.employee_type"
|
||||
```
|
||||
|
||||
- Set Redirect URI, if your provider requires it
|
||||
- Set a redirect url = `<your proxy base url>/sso/callback`
|
||||
```shell
|
||||
|
|
|
|||
|
|
@ -548,6 +548,10 @@ router_settings:
|
|||
| DEFAULT_MCP_SEMANTIC_FILTER_EMBEDDING_MODEL | Default embedding model for MCP semantic tool filtering. Default is "text-embedding-3-small"
|
||||
| DEFAULT_MCP_SEMANTIC_FILTER_SIMILARITY_THRESHOLD | Default similarity threshold for MCP semantic tool filtering. Default is 0.3
|
||||
| DEFAULT_MCP_SEMANTIC_FILTER_TOP_K | Default number of top results to return for MCP semantic tool filtering. Default is 10
|
||||
| MCP_OAUTH2_TOKEN_CACHE_DEFAULT_TTL | Default TTL in seconds for MCP OAuth2 token cache. Default is 3600
|
||||
| MCP_OAUTH2_TOKEN_CACHE_MAX_SIZE | Maximum number of entries in MCP OAuth2 token cache. Default is 200
|
||||
| MCP_OAUTH2_TOKEN_CACHE_MIN_TTL | Minimum TTL in seconds for MCP OAuth2 token cache. Default is 10
|
||||
| MCP_OAUTH2_TOKEN_EXPIRY_BUFFER_SECONDS | Seconds to subtract from token expiry when computing cache TTL. Default is 60
|
||||
| DEFAULT_MOCK_RESPONSE_COMPLETION_TOKEN_COUNT | Default token count for mock response completions. Default is 20
|
||||
| DEFAULT_MOCK_RESPONSE_PROMPT_TOKEN_COUNT | Default token count for mock response prompts. Default is 10
|
||||
| DEFAULT_MODEL_CREATED_AT_TIME | Default creation timestamp for models. Default is 1677610602
|
||||
|
|
@ -640,6 +644,7 @@ router_settings:
|
|||
| GENERIC_TOKEN_ENDPOINT | Token endpoint for generic OAuth providers
|
||||
| GENERIC_USER_DISPLAY_NAME_ATTRIBUTE | Attribute for user's display name in generic auth
|
||||
| GENERIC_USER_EMAIL_ATTRIBUTE | Attribute for user's email in generic auth
|
||||
| GENERIC_USER_EXTRA_ATTRIBUTES | Comma-separated list of additional fields to extract from generic SSO provider response (e.g., "department,employee_id,groups"). Accessible via `CustomOpenID.extra_fields` in custom SSO handlers. Supports dot notation for nested fields
|
||||
| GENERIC_USER_FIRST_NAME_ATTRIBUTE | Attribute for user's first name in generic auth
|
||||
| GENERIC_USER_ID_ATTRIBUTE | Attribute for user ID in generic auth
|
||||
| GENERIC_USER_LAST_NAME_ATTRIBUTE | Attribute for user's last name in generic auth
|
||||
|
|
@ -779,6 +784,7 @@ router_settings:
|
|||
| LITELLM_USER_AGENT | Custom user agent string for LiteLLM API requests. Used for partner telemetry attribution
|
||||
| LITELLM_PRINT_STANDARD_LOGGING_PAYLOAD | If true, prints the standard logging payload to the console - useful for debugging
|
||||
| LITELM_ENVIRONMENT | Environment for LiteLLM Instance. This is currently only logged to DeepEval to determine the environment for DeepEval integration.
|
||||
| LITELLM_ASYNCIO_QUEUE_MAXSIZE | Maximum size for asyncio queues (e.g. log queues, spend update queues, and cookbook examples such as realtime audio in `nova_sonic_realtime.py`). Bounds in-memory growth to prevent OOM. Default is 1000.
|
||||
| LOGFIRE_TOKEN | Token for Logfire logging service
|
||||
| LOGFIRE_BASE_URL | Base URL for Logfire logging service (useful for self hosted deployments)
|
||||
| LOGGING_WORKER_CONCURRENCY | Maximum number of concurrent coroutine slots for the logging worker on the asyncio event loop. Default is 100. Setting too high will flood the event loop with logging tasks which will lower the overall latency of the requests.
|
||||
|
|
|
|||
|
|
@ -142,6 +142,18 @@ async def custom_sso_handler(userIDPInfo: OpenID) -> SSOUserDefinedValues:
|
|||
f"No ID found for user. userIDPInfo.id is None {userIDPInfo}"
|
||||
)
|
||||
|
||||
#################################################
|
||||
# Access extra fields from SSO provider (requires GENERIC_USER_EXTRA_ATTRIBUTES env var)
|
||||
# Example: Set GENERIC_USER_EXTRA_ATTRIBUTES="department,employee_id,groups"
|
||||
extra_fields = getattr(userIDPInfo, 'extra_fields', None) or {}
|
||||
user_department = extra_fields.get("department")
|
||||
employee_id = extra_fields.get("employee_id")
|
||||
user_groups = extra_fields.get("groups", [])
|
||||
|
||||
print(f"User department: {user_department}") # noqa
|
||||
print(f"Employee ID: {employee_id}") # noqa
|
||||
print(f"User groups: {user_groups}") # noqa
|
||||
#################################################
|
||||
|
||||
#################################################
|
||||
# Run your custom code / logic here
|
||||
|
|
|
|||
|
|
@ -1108,6 +1108,17 @@ const sidebars = {
|
|||
"troubleshoot/max_callbacks",
|
||||
],
|
||||
},
|
||||
{
|
||||
type: "category",
|
||||
label: "Blog",
|
||||
items: [
|
||||
{
|
||||
type: "link",
|
||||
label: "Incident: Broken Model Cost Map",
|
||||
href: "/blog/model-cost-map-incident",
|
||||
},
|
||||
],
|
||||
},
|
||||
],
|
||||
};
|
||||
|
||||
|
|
|
|||
|
|
@ -899,49 +899,49 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
batch_id=response.id, model_id=model_id
|
||||
)
|
||||
|
||||
if (
|
||||
response.output_file_id and model_id
|
||||
): # return a file id with the model_id and output_file_id
|
||||
original_output_file_id = response.output_file_id
|
||||
response.output_file_id = self.get_unified_output_file_id(
|
||||
output_file_id=response.output_file_id,
|
||||
model_id=model_id,
|
||||
model_name=model_name,
|
||||
)
|
||||
|
||||
# Fetch the actual file object for the output file
|
||||
file_object = None
|
||||
try:
|
||||
# Use litellm to retrieve the file object from the provider
|
||||
from litellm import afile_retrieve
|
||||
file_object = await afile_retrieve(
|
||||
custom_llm_provider=model_name.split("/")[0] if model_name and "/" in model_name else "openai",
|
||||
file_id=original_output_file_id
|
||||
# Handle both output_file_id and error_file_id
|
||||
for file_attr in ["output_file_id", "error_file_id"]:
|
||||
file_id_value = getattr(response, file_attr, None)
|
||||
if file_id_value and model_id:
|
||||
original_file_id = file_id_value
|
||||
unified_file_id = self.get_unified_output_file_id(
|
||||
output_file_id=original_file_id,
|
||||
model_id=model_id,
|
||||
model_name=model_name,
|
||||
)
|
||||
verbose_logger.debug(
|
||||
f"Successfully retrieved file object for output_file_id={original_output_file_id}"
|
||||
setattr(response, file_attr, unified_file_id)
|
||||
|
||||
# Fetch the actual file object from the provider
|
||||
file_object = None
|
||||
try:
|
||||
# Use litellm to retrieve the file object from the provider
|
||||
from litellm import afile_retrieve
|
||||
file_object = await afile_retrieve(
|
||||
custom_llm_provider=model_name.split("/")[0] if model_name and "/" in model_name else "openai",
|
||||
file_id=original_file_id
|
||||
)
|
||||
verbose_logger.debug(
|
||||
f"Successfully retrieved file object for {file_attr}={original_file_id}"
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_logger.warning(
|
||||
f"Failed to retrieve file object for {file_attr}={original_file_id}: {str(e)}. Storing with None and will fetch on-demand."
|
||||
)
|
||||
|
||||
await self.store_unified_file_id(
|
||||
file_id=unified_file_id,
|
||||
file_object=file_object,
|
||||
litellm_parent_otel_span=user_api_key_dict.parent_otel_span,
|
||||
model_mappings={model_id: original_file_id},
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_logger.warning(
|
||||
f"Failed to retrieve file object for output_file_id={original_output_file_id}: {str(e)}. Storing with None and will fetch on-demand."
|
||||
)
|
||||
|
||||
await self.store_unified_file_id(
|
||||
file_id=response.output_file_id,
|
||||
file_object=file_object,
|
||||
litellm_parent_otel_span=user_api_key_dict.parent_otel_span,
|
||||
model_mappings={model_id: original_output_file_id},
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
)
|
||||
asyncio.create_task(
|
||||
self.store_unified_object_id(
|
||||
unified_object_id=response.id,
|
||||
file_object=response,
|
||||
litellm_parent_otel_span=user_api_key_dict.parent_otel_span,
|
||||
model_object_id=original_response_id,
|
||||
file_purpose="batch",
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
)
|
||||
await self.store_unified_object_id(
|
||||
unified_object_id=response.id,
|
||||
file_object=response,
|
||||
litellm_parent_otel_span=user_api_key_dict.parent_otel_span,
|
||||
model_object_id=original_response_id,
|
||||
file_purpose="batch",
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
)
|
||||
elif isinstance(response, LiteLLMFineTuningJob):
|
||||
## Check if unified_file_id is in the response
|
||||
|
|
@ -958,15 +958,13 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
response.id = self.get_unified_generic_response_id(
|
||||
model_id=model_id, generic_response_id=response.id
|
||||
)
|
||||
asyncio.create_task(
|
||||
self.store_unified_object_id(
|
||||
unified_object_id=response.id,
|
||||
file_object=response,
|
||||
litellm_parent_otel_span=user_api_key_dict.parent_otel_span,
|
||||
model_object_id=original_response_id,
|
||||
file_purpose="fine-tune",
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
)
|
||||
await self.store_unified_object_id(
|
||||
unified_object_id=response.id,
|
||||
file_object=response,
|
||||
litellm_parent_otel_span=user_api_key_dict.parent_otel_span,
|
||||
model_object_id=original_response_id,
|
||||
file_purpose="fine-tune",
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
)
|
||||
elif isinstance(response, AsyncCursorPage):
|
||||
"""
|
||||
|
|
|
|||
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.34-py3-none-any.whl
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.34-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.34.tar.gz
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.34.tar.gz
vendored
Normal file
Binary file not shown.
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "litellm-proxy-extras"
|
||||
version = "0.4.33"
|
||||
version = "0.4.34"
|
||||
description = "Additional files for the LiteLLM Proxy. Reduces the size of the main litellm package."
|
||||
authors = ["BerriAI"]
|
||||
readme = "README.md"
|
||||
|
|
@ -22,7 +22,7 @@ requires = ["poetry-core"]
|
|||
build-backend = "poetry.core.masonry.api"
|
||||
|
||||
[tool.commitizen]
|
||||
version = "0.4.33"
|
||||
version = "0.4.34"
|
||||
version_files = [
|
||||
"pyproject.toml:version",
|
||||
"../requirements.txt:litellm-proxy-extras==",
|
||||
|
|
|
|||
|
|
@ -1393,6 +1393,7 @@ if TYPE_CHECKING:
|
|||
from .llms.litellm_proxy.responses.transformation import LiteLLMProxyResponsesAPIConfig as LiteLLMProxyResponsesAPIConfig
|
||||
from .llms.volcengine.responses.transformation import VolcEngineResponsesAPIConfig as VolcEngineResponsesAPIConfig
|
||||
from .llms.manus.responses.transformation import ManusResponsesAPIConfig as ManusResponsesAPIConfig
|
||||
from .llms.perplexity.responses.transformation import PerplexityResponsesConfig as PerplexityResponsesConfig
|
||||
from .llms.gemini.interactions.transformation import GoogleAIStudioInteractionsConfig as GoogleAIStudioInteractionsConfig
|
||||
from .llms.openai.chat.o_series_transformation import OpenAIOSeriesConfig as OpenAIOSeriesConfig, OpenAIOSeriesConfig as OpenAIO1Config
|
||||
from .llms.anthropic.skills.transformation import AnthropicSkillsConfig as AnthropicSkillsConfig
|
||||
|
|
|
|||
|
|
@ -226,6 +226,7 @@ LLM_CONFIG_NAMES = (
|
|||
"XAIResponsesAPIConfig",
|
||||
"LiteLLMProxyResponsesAPIConfig",
|
||||
"VolcEngineResponsesAPIConfig",
|
||||
"PerplexityResponsesConfig",
|
||||
"GoogleAIStudioInteractionsConfig",
|
||||
"OpenAIOSeriesConfig",
|
||||
"AnthropicSkillsConfig",
|
||||
|
|
@ -274,6 +275,7 @@ LLM_CONFIG_NAMES = (
|
|||
"LmStudioEmbeddingConfig",
|
||||
"NscaleConfig",
|
||||
"PerplexityChatConfig",
|
||||
"PerplexityResponsesConfig",
|
||||
"AzureOpenAIO1Config",
|
||||
"IBMWatsonXAIConfig",
|
||||
"IBMWatsonXChatConfig",
|
||||
|
|
@ -901,6 +903,10 @@ _LLM_CONFIGS_IMPORT_MAP = {
|
|||
".llms.manus.responses.transformation",
|
||||
"ManusResponsesAPIConfig",
|
||||
),
|
||||
"PerplexityResponsesConfig": (
|
||||
".llms.perplexity.responses.transformation",
|
||||
"PerplexityResponsesConfig",
|
||||
),
|
||||
"GoogleAIStudioInteractionsConfig": (
|
||||
".llms.gemini.interactions.transformation",
|
||||
"GoogleAIStudioInteractionsConfig",
|
||||
|
|
|
|||
|
|
@ -1,9 +1,13 @@
|
|||
import json
|
||||
import ast
|
||||
import logging
|
||||
import os
|
||||
import sys
|
||||
from datetime import datetime
|
||||
from logging import Formatter
|
||||
from typing import Any, Dict, Optional
|
||||
|
||||
from litellm.litellm_core_utils.safe_json_dumps import safe_dumps
|
||||
from litellm.litellm_core_utils.safe_json_loads import safe_json_loads
|
||||
|
||||
set_verbose = False
|
||||
|
||||
|
|
@ -19,6 +23,67 @@ handler = logging.StreamHandler()
|
|||
handler.setLevel(numeric_level)
|
||||
|
||||
|
||||
def _try_parse_json_message(message: str) -> Optional[Dict[str, Any]]:
|
||||
"""
|
||||
Try to parse a log message as JSON. Returns parsed dict if valid, else None.
|
||||
Handles messages that are entirely valid JSON (e.g. json.dumps output).
|
||||
Uses shared safe_json_loads for consistent error handling.
|
||||
"""
|
||||
if not message or not isinstance(message, str):
|
||||
return None
|
||||
msg_stripped = message.strip()
|
||||
if not (msg_stripped.startswith("{") or msg_stripped.startswith("[")):
|
||||
return None
|
||||
parsed = safe_json_loads(message, default=None)
|
||||
if parsed is None or not isinstance(parsed, dict):
|
||||
return None
|
||||
return parsed
|
||||
|
||||
|
||||
def _try_parse_embedded_python_dict(message: str) -> Optional[Dict[str, Any]]:
|
||||
"""
|
||||
Try to find and parse a Python dict repr (e.g. str(d) or repr(d)) embedded in
|
||||
the message. Handles patterns like:
|
||||
"get_available_deployment for model: X, Selected deployment: {'model_name': '...', ...} for model: X"
|
||||
Uses ast.literal_eval for safe parsing. Returns the parsed dict or None.
|
||||
"""
|
||||
if not message or not isinstance(message, str) or "{" not in message:
|
||||
return None
|
||||
i = 0
|
||||
while i < len(message):
|
||||
start = message.find("{", i)
|
||||
if start == -1:
|
||||
break
|
||||
depth = 0
|
||||
for j in range(start, len(message)):
|
||||
c = message[j]
|
||||
if c == "{":
|
||||
depth += 1
|
||||
elif c == "}":
|
||||
depth -= 1
|
||||
if depth == 0:
|
||||
substr = message[start : j + 1]
|
||||
try:
|
||||
result = ast.literal_eval(substr)
|
||||
if isinstance(result, dict) and len(result) > 0:
|
||||
return result
|
||||
except (ValueError, SyntaxError, TypeError):
|
||||
pass
|
||||
break
|
||||
i = start + 1
|
||||
return None
|
||||
|
||||
|
||||
# Standard LogRecord attribute names - used to identify 'extra' fields.
|
||||
# Derived at runtime so we automatically include version-specific attrs (e.g. taskName).
|
||||
def _get_standard_record_attrs() -> frozenset:
|
||||
"""Standard LogRecord attribute names - excludes extra keys from logger.debug(..., extra={...})."""
|
||||
return frozenset(logging.LogRecord("", 0, "", 0, "", (), None).__dict__.keys())
|
||||
|
||||
|
||||
_STANDARD_RECORD_ATTRS = _get_standard_record_attrs()
|
||||
|
||||
|
||||
class JsonFormatter(Formatter):
|
||||
def __init__(self):
|
||||
super(JsonFormatter, self).__init__()
|
||||
|
|
@ -29,16 +94,31 @@ class JsonFormatter(Formatter):
|
|||
return dt.isoformat()
|
||||
|
||||
def format(self, record):
|
||||
json_record = {
|
||||
"message": record.getMessage(),
|
||||
message_str = record.getMessage()
|
||||
json_record: Dict[str, Any] = {
|
||||
"message": message_str,
|
||||
"level": record.levelname,
|
||||
"timestamp": self.formatTime(record),
|
||||
}
|
||||
|
||||
# Parse embedded JSON or Python dict repr in message so sub-fields become first-class properties
|
||||
parsed = _try_parse_json_message(message_str)
|
||||
if parsed is None:
|
||||
parsed = _try_parse_embedded_python_dict(message_str)
|
||||
if parsed is not None:
|
||||
for key, value in parsed.items():
|
||||
if key not in json_record:
|
||||
json_record[key] = value
|
||||
|
||||
# Include extra attributes passed via logger.debug("msg", extra={...})
|
||||
for key, value in record.__dict__.items():
|
||||
if key not in _STANDARD_RECORD_ATTRS and key not in json_record:
|
||||
json_record[key] = value
|
||||
|
||||
if record.exc_info:
|
||||
json_record["stacktrace"] = self.formatException(record.exc_info)
|
||||
|
||||
return json.dumps(json_record)
|
||||
return safe_dumps(json_record)
|
||||
|
||||
|
||||
# Function to set up exception handlers for JSON logging
|
||||
|
|
@ -169,15 +249,15 @@ def _initialize_loggers_with_handler(handler: logging.Handler):
|
|||
def _get_uvicorn_json_log_config():
|
||||
"""
|
||||
Generate a uvicorn log_config dictionary that applies JSON formatting to all loggers.
|
||||
|
||||
|
||||
This ensures that uvicorn's access logs, error logs, and all application logs
|
||||
are formatted as JSON when json_logs is enabled.
|
||||
"""
|
||||
json_formatter_class = "litellm._logging.JsonFormatter"
|
||||
|
||||
|
||||
# Use the module-level log_level variable for consistency
|
||||
uvicorn_log_level = log_level.upper()
|
||||
|
||||
|
||||
log_config = {
|
||||
"version": 1,
|
||||
"disable_existing_loggers": False,
|
||||
|
|
@ -222,7 +302,7 @@ def _get_uvicorn_json_log_config():
|
|||
},
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
return log_config
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -48,6 +48,14 @@ DEFAULT_REPLICATE_POLLING_DELAY_SECONDS = int(
|
|||
os.getenv("DEFAULT_REPLICATE_POLLING_DELAY_SECONDS", 1)
|
||||
)
|
||||
DEFAULT_IMAGE_TOKEN_COUNT = int(os.getenv("DEFAULT_IMAGE_TOKEN_COUNT", 250))
|
||||
|
||||
# Model cost map validation constants
|
||||
MODEL_COST_MAP_MIN_MODEL_COUNT = int(
|
||||
os.getenv("MODEL_COST_MAP_MIN_MODEL_COUNT", 50)
|
||||
) # Minimum number of models a fetched cost map must contain to be considered valid
|
||||
MODEL_COST_MAP_MAX_SHRINK_RATIO = float(
|
||||
os.getenv("MODEL_COST_MAP_MAX_SHRINK_RATIO", 0.5)
|
||||
) # Maximum allowed shrinkage ratio vs local backup (0.5 = reject if fetched map is <50% of backup)
|
||||
DEFAULT_IMAGE_WIDTH = int(os.getenv("DEFAULT_IMAGE_WIDTH", 300))
|
||||
DEFAULT_IMAGE_HEIGHT = int(os.getenv("DEFAULT_IMAGE_HEIGHT", 300))
|
||||
# Maximum size for image URL downloads in MB (default 50MB, set to 0 to disable limit)
|
||||
|
|
@ -205,6 +213,10 @@ REDIS_DAILY_AGENT_SPEND_UPDATE_BUFFER_KEY = "litellm_daily_agent_spend_update_bu
|
|||
REDIS_DAILY_TAG_SPEND_UPDATE_BUFFER_KEY = "litellm_daily_tag_spend_update_buffer"
|
||||
MAX_REDIS_BUFFER_DEQUEUE_COUNT = int(os.getenv("MAX_REDIS_BUFFER_DEQUEUE_COUNT", 100))
|
||||
MAX_SIZE_IN_MEMORY_QUEUE = int(os.getenv("MAX_SIZE_IN_MEMORY_QUEUE", 2000))
|
||||
# Bounds asyncio.Queue() instances (log queues, spend update queues, etc.) to prevent unbounded memory growth
|
||||
LITELLM_ASYNCIO_QUEUE_MAXSIZE = int(
|
||||
os.getenv("LITELLM_ASYNCIO_QUEUE_MAXSIZE", 1000)
|
||||
)
|
||||
MAX_IN_MEMORY_QUEUE_FLUSH_COUNT = int(
|
||||
os.getenv("MAX_IN_MEMORY_QUEUE_FLUSH_COUNT", 1000)
|
||||
)
|
||||
|
|
|
|||
|
|
@ -103,10 +103,15 @@ class CBFTransformer:
|
|||
# Use team_alias if available, otherwise team_id, otherwise fallback to 'unknown'
|
||||
entity_id = str(team_alias) if team_alias else (str(team_id) if team_id else 'unknown')
|
||||
|
||||
# Get alias fields if they exist
|
||||
api_key_alias = row.get('api_key_alias')
|
||||
organization_alias = row.get('organization_alias')
|
||||
project_alias = row.get('project_alias')
|
||||
user_alias = row.get('user_alias')
|
||||
|
||||
dimensions = {
|
||||
'entity_type': CZEntityType.TEAM.value,
|
||||
'entity_id': entity_id,
|
||||
'team_id': str(team_id) if team_id else 'unknown',
|
||||
'team_alias': str(team_alias) if team_alias else 'unknown',
|
||||
'model': model,
|
||||
'model_group': str(row.get('model_group', '')),
|
||||
|
|
@ -119,28 +124,37 @@ class CBFTransformer:
|
|||
'failed_requests': str(row.get('failed_requests', 0)),
|
||||
'cache_creation_tokens': str(row.get('cache_creation_input_tokens', 0)),
|
||||
'cache_read_tokens': str(row.get('cache_read_input_tokens', 0)),
|
||||
'organization_alias': str(organization_alias) if organization_alias else '',
|
||||
'project_alias': str(project_alias) if project_alias else '',
|
||||
'user_alias': str(user_alias) if user_alias else '',
|
||||
}
|
||||
|
||||
# Extract CZRN components to populate corresponding CBF columns
|
||||
czrn_components = self.czrn_generator.extract_components(resource_id)
|
||||
service_type, provider, region, owner_account_id, resource_type, cloud_local_id = czrn_components
|
||||
|
||||
# Build resource/account as concat of api_key_alias and api_key_prefix
|
||||
resource_account = f"{api_key_alias}|{api_key_hash}" if api_key_alias else api_key_hash
|
||||
|
||||
# CloudZero CBF format with proper column names
|
||||
cbf_record = {
|
||||
# Required CBF fields
|
||||
'time/usage_start': usage_date.isoformat() if usage_date else None, # Required: ISO-formatted UTC datetime
|
||||
'cost/cost': float(row.get('spend', 0.0)), # Required: billed cost
|
||||
'resource/id': resource_id, # Required when resource tags are present
|
||||
'resource/id': model, # Send model name
|
||||
|
||||
# Usage metrics for token consumption
|
||||
'usage/amount': total_tokens, # Numeric value of tokens consumed
|
||||
'usage/units': 'tokens', # Description of token units
|
||||
|
||||
# CBF fields that correspond to CZRN components
|
||||
'resource/service': service_type, # Maps to CZRN service-type (litellm)
|
||||
'resource/account': owner_account_id, # Maps to CZRN owner-account-id (entity_id)
|
||||
# CBF fields - updated per LIT-1907
|
||||
'resource/service': str(row.get('model_group', '')), # Send model_group
|
||||
'resource/account': resource_account, # Send api_key_alias|api_key_prefix
|
||||
'resource/region': region, # Maps to CZRN region (cross-region)
|
||||
'resource/usage_family': resource_type, # Maps to CZRN resource-type (llm-usage)
|
||||
'resource/usage_family': str(row.get('custom_llm_provider', '')), # Send provider
|
||||
|
||||
# Action field
|
||||
'action/operation': str(team_id) if team_id else '', # Send team_id
|
||||
|
||||
# Line item details
|
||||
'lineitem/type': 'Usage', # Standard usage line item
|
||||
|
|
@ -155,13 +169,11 @@ class CBFTransformer:
|
|||
if value and value != 'N/A' and value != 'unknown': # Only add meaningful tags
|
||||
cbf_record[f'resource/tag:{key}'] = str(value)
|
||||
|
||||
# Add token breakdown as resource tags for analysis
|
||||
# Add token breakdown as resource tags for analysis (excluding total_tokens per LIT-1907)
|
||||
if prompt_tokens > 0:
|
||||
cbf_record['resource/tag:prompt_tokens'] = str(prompt_tokens)
|
||||
if completion_tokens > 0:
|
||||
cbf_record['resource/tag:completion_tokens'] = str(completion_tokens)
|
||||
if total_tokens > 0:
|
||||
cbf_record['resource/tag:total_tokens'] = str(total_tokens)
|
||||
|
||||
return CBFRecord(cbf_record)
|
||||
|
||||
|
|
|
|||
|
|
@ -616,6 +616,7 @@ class CustomGuardrail(CustomLogger):
|
|||
end_time: Optional[float] = None,
|
||||
duration: Optional[float] = None,
|
||||
event_type: Optional[GuardrailEventHooks] = None,
|
||||
original_inputs: Optional[Dict] = None,
|
||||
):
|
||||
"""
|
||||
Add StandardLoggingGuardrailInformation to the request data
|
||||
|
|
@ -625,6 +626,17 @@ class CustomGuardrail(CustomLogger):
|
|||
# Convert None to empty dict to satisfy type requirements
|
||||
guardrail_response = {} if response is None else response
|
||||
|
||||
# For apply_guardrail functions in custom_code_guardrail scenario,
|
||||
# simplify the logged response to "allow", "deny", or "mask"
|
||||
if original_inputs is not None and isinstance(response, dict):
|
||||
# Check if inputs were modified by comparing them
|
||||
if self._inputs_were_modified(original_inputs, response):
|
||||
guardrail_response = "mask"
|
||||
else:
|
||||
guardrail_response = "allow"
|
||||
|
||||
verbose_logger.debug(f"Guardrail response: {response}")
|
||||
|
||||
self.add_standard_logging_guardrail_information_to_request_data(
|
||||
guardrail_json_response=guardrail_response,
|
||||
request_data=request_data,
|
||||
|
|
@ -650,8 +662,14 @@ class CustomGuardrail(CustomLogger):
|
|||
|
||||
This gets logged on downsteam Langfuse, DataDog, etc.
|
||||
"""
|
||||
# For custom_code_guardrail scenario, log as "deny" instead of full exception
|
||||
# Check if this is from custom_code_guardrail by checking the class name
|
||||
guardrail_response: Union[Exception, str] = e
|
||||
if "CustomCodeGuardrail" in self.__class__.__name__:
|
||||
guardrail_response = "deny"
|
||||
|
||||
self.add_standard_logging_guardrail_information_to_request_data(
|
||||
guardrail_json_response=e,
|
||||
guardrail_json_response=guardrail_response,
|
||||
request_data=request_data,
|
||||
guardrail_status="guardrail_failed_to_respond",
|
||||
duration=duration,
|
||||
|
|
@ -661,6 +679,25 @@ class CustomGuardrail(CustomLogger):
|
|||
)
|
||||
raise e
|
||||
|
||||
def _inputs_were_modified(self, original_inputs: Dict, response: Dict) -> bool:
|
||||
"""
|
||||
Compare original inputs with response to determine if content was modified.
|
||||
|
||||
Returns True if the inputs were modified (mask scenario), False otherwise (allow scenario).
|
||||
"""
|
||||
# Get all keys from both dictionaries
|
||||
all_keys = set(original_inputs.keys()) | set(response.keys())
|
||||
|
||||
# Compare each key's value
|
||||
for key in all_keys:
|
||||
original_value = original_inputs.get(key)
|
||||
response_value = response.get(key)
|
||||
if original_value != response_value:
|
||||
return True
|
||||
|
||||
# No modifications detected
|
||||
return False
|
||||
|
||||
def mask_content_in_string(
|
||||
self,
|
||||
content_string: str,
|
||||
|
|
@ -768,6 +805,12 @@ def log_guardrail_information(func):
|
|||
self: CustomGuardrail = args[0]
|
||||
request_data: dict = kwargs.get("data") or kwargs.get("request_data") or {}
|
||||
event_type = _infer_event_type_from_function_name(func.__name__)
|
||||
|
||||
# Store original inputs for comparison (for apply_guardrail functions)
|
||||
original_inputs = None
|
||||
if func.__name__ == "apply_guardrail" and "inputs" in kwargs:
|
||||
original_inputs = kwargs.get("inputs")
|
||||
|
||||
try:
|
||||
response = await func(*args, **kwargs)
|
||||
return self._process_response(
|
||||
|
|
@ -777,6 +820,7 @@ def log_guardrail_information(func):
|
|||
end_time=datetime.now().timestamp(),
|
||||
duration=(datetime.now() - start_time).total_seconds(),
|
||||
event_type=event_type,
|
||||
original_inputs=original_inputs,
|
||||
)
|
||||
except Exception as e:
|
||||
return self._process_error(
|
||||
|
|
@ -794,6 +838,12 @@ def log_guardrail_information(func):
|
|||
self: CustomGuardrail = args[0]
|
||||
request_data: dict = kwargs.get("data") or kwargs.get("request_data") or {}
|
||||
event_type = _infer_event_type_from_function_name(func.__name__)
|
||||
|
||||
# Store original inputs for comparison (for apply_guardrail functions)
|
||||
original_inputs = None
|
||||
if func.__name__ == "apply_guardrail" and "inputs" in kwargs:
|
||||
original_inputs = kwargs.get("inputs")
|
||||
|
||||
try:
|
||||
response = func(*args, **kwargs)
|
||||
return self._process_response(
|
||||
|
|
@ -801,6 +851,7 @@ def log_guardrail_information(func):
|
|||
request_data=request_data,
|
||||
duration=(datetime.now() - start_time).total_seconds(),
|
||||
event_type=event_type,
|
||||
original_inputs=original_inputs,
|
||||
)
|
||||
except Exception as e:
|
||||
return self._process_error(
|
||||
|
|
|
|||
|
|
@ -9,6 +9,7 @@ from typing import TYPE_CHECKING, Any, Dict, List, Optional, Tuple
|
|||
from urllib.parse import quote
|
||||
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.constants import LITELLM_ASYNCIO_QUEUE_MAXSIZE
|
||||
from litellm.integrations.additional_logging_utils import AdditionalLoggingUtils
|
||||
from litellm.integrations.gcs_bucket.gcs_bucket_base import GCSBucketBase
|
||||
from litellm.proxy._types import CommonProxyErrors
|
||||
|
|
@ -41,7 +42,9 @@ class GCSBucketLogger(GCSBucketBase, AdditionalLoggingUtils):
|
|||
batch_size=self.batch_size,
|
||||
flush_interval=self.flush_interval,
|
||||
)
|
||||
self.log_queue: asyncio.Queue[GCSLogQueueItem] = asyncio.Queue() # type: ignore[assignment]
|
||||
self.log_queue: asyncio.Queue[GCSLogQueueItem] = asyncio.Queue( # type: ignore[assignment]
|
||||
maxsize=LITELLM_ASYNCIO_QUEUE_MAXSIZE
|
||||
)
|
||||
asyncio.create_task(self.periodic_flush())
|
||||
AdditionalLoggingUtils.__init__(self)
|
||||
|
||||
|
|
@ -69,6 +72,9 @@ class GCSBucketLogger(GCSBucketBase, AdditionalLoggingUtils):
|
|||
)
|
||||
if logging_payload is None:
|
||||
raise ValueError("standard_logging_object not found in kwargs")
|
||||
# When queue is at maxsize, flush immediately to make room (no blocking, no data dropped)
|
||||
if self.log_queue.full():
|
||||
await self.flush_queue()
|
||||
await self.log_queue.put(
|
||||
GCSLogQueueItem(
|
||||
payload=logging_payload, kwargs=kwargs, response_obj=response_obj
|
||||
|
|
@ -91,9 +97,9 @@ class GCSBucketLogger(GCSBucketBase, AdditionalLoggingUtils):
|
|||
)
|
||||
if logging_payload is None:
|
||||
raise ValueError("standard_logging_object not found in kwargs")
|
||||
# Add to logging queue - this will be flushed periodically
|
||||
# Use asyncio.Queue.put() for thread-safe concurrent access
|
||||
# If queue is full, this will block until space is available (backpressure)
|
||||
# When queue is at maxsize, flush immediately to make room (no blocking, no data dropped)
|
||||
if self.log_queue.full():
|
||||
await self.flush_queue()
|
||||
await self.log_queue.put(
|
||||
GCSLogQueueItem(
|
||||
payload=logging_payload, kwargs=kwargs, response_obj=response_obj
|
||||
|
|
|
|||
|
|
@ -5,6 +5,10 @@ from typing import TYPE_CHECKING, Any, Dict, List, Optional, Union, cast
|
|||
|
||||
import litellm
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.integrations._types.open_inference import (
|
||||
OpenInferenceSpanKindValues,
|
||||
SpanAttributes,
|
||||
)
|
||||
from litellm.integrations.custom_logger import CustomLogger
|
||||
from litellm.litellm_core_utils.safe_json_dumps import safe_dumps
|
||||
from litellm.secret_managers.main import get_secret_bool
|
||||
|
|
@ -17,10 +21,6 @@ from litellm.types.utils import (
|
|||
StandardCallbackDynamicParams,
|
||||
StandardLoggingPayload,
|
||||
)
|
||||
from litellm.integrations._types.open_inference import (
|
||||
OpenInferenceSpanKindValues,
|
||||
SpanAttributes,
|
||||
)
|
||||
|
||||
# OpenTelemetry imports moved to individual functions to avoid import errors when not installed
|
||||
|
||||
|
|
@ -40,7 +40,9 @@ if TYPE_CHECKING:
|
|||
Context = Union[_Context, Any]
|
||||
SpanExporter = Union[_SpanExporter, Any]
|
||||
UserAPIKeyAuth = Union[_UserAPIKeyAuth, Any]
|
||||
ManagementEndpointLoggingPayload = Union[_ManagementEndpointLoggingPayload, Any]
|
||||
ManagementEndpointLoggingPayload = Union[
|
||||
_ManagementEndpointLoggingPayload, Any
|
||||
]
|
||||
else:
|
||||
Span = Any
|
||||
Tracer = Any
|
||||
|
|
@ -70,6 +72,13 @@ class OpenTelemetryConfig:
|
|||
model_id: Optional[str] = None
|
||||
|
||||
def __post_init__(self) -> None:
|
||||
# If endpoint is specified but exporter is still the default "console",
|
||||
# automatically infer "otlp_http" to send traces to the endpoint.
|
||||
# This fixes an issue where UI-configured OTEL settings would default
|
||||
# to console output instead of sending traces to the configured endpoint.
|
||||
if self.endpoint and isinstance(self.exporter, str) and self.exporter == "console":
|
||||
self.exporter = "otlp_http"
|
||||
|
||||
if not self.service_name:
|
||||
self.service_name = os.getenv("OTEL_SERVICE_NAME", "litellm")
|
||||
if not self.deployment_environment:
|
||||
|
|
@ -95,12 +104,16 @@ class OpenTelemetryConfig:
|
|||
exporter = os.getenv(
|
||||
"OTEL_EXPORTER_OTLP_PROTOCOL", os.getenv("OTEL_EXPORTER", "console")
|
||||
)
|
||||
endpoint = os.getenv("OTEL_EXPORTER_OTLP_ENDPOINT", os.getenv("OTEL_ENDPOINT"))
|
||||
endpoint = os.getenv(
|
||||
"OTEL_EXPORTER_OTLP_ENDPOINT", os.getenv("OTEL_ENDPOINT")
|
||||
)
|
||||
headers = os.getenv(
|
||||
"OTEL_EXPORTER_OTLP_HEADERS", os.getenv("OTEL_HEADERS")
|
||||
) # example: OTEL_HEADERS=x-honeycomb-team=B85YgLm96***"
|
||||
enable_metrics: bool = (
|
||||
os.getenv("LITELLM_OTEL_INTEGRATION_ENABLE_METRICS", "false").lower()
|
||||
os.getenv(
|
||||
"LITELLM_OTEL_INTEGRATION_ENABLE_METRICS", "false"
|
||||
).lower()
|
||||
== "true"
|
||||
)
|
||||
enable_events: bool = (
|
||||
|
|
@ -108,7 +121,9 @@ class OpenTelemetryConfig:
|
|||
== "true"
|
||||
)
|
||||
service_name = os.getenv("OTEL_SERVICE_NAME", "litellm")
|
||||
deployment_environment = os.getenv("OTEL_ENVIRONMENT_NAME", "production")
|
||||
deployment_environment = os.getenv(
|
||||
"OTEL_ENVIRONMENT_NAME", "production"
|
||||
)
|
||||
model_id = os.getenv("OTEL_MODEL_ID", service_name)
|
||||
|
||||
if exporter == "in_memory":
|
||||
|
|
@ -157,7 +172,9 @@ class OpenTelemetry(CustomLogger):
|
|||
logging.getLogger(__name__)
|
||||
|
||||
# Enable OpenTelemetry logging
|
||||
otel_exporter_logger = logging.getLogger("opentelemetry.sdk.trace.export")
|
||||
otel_exporter_logger = logging.getLogger(
|
||||
"opentelemetry.sdk.trace.export"
|
||||
)
|
||||
otel_exporter_logger.setLevel(logging.DEBUG)
|
||||
|
||||
# init CustomLogger params
|
||||
|
|
@ -253,7 +270,9 @@ class OpenTelemetry(CustomLogger):
|
|||
# Don't call set_provider to preserve existing context
|
||||
else:
|
||||
# Default proxy provider or unknown type, create our own
|
||||
verbose_logger.debug("OpenTelemetry: Creating new %s", provider_name)
|
||||
verbose_logger.debug(
|
||||
"OpenTelemetry: Creating new %s", provider_name
|
||||
)
|
||||
provider = create_new_provider_fn()
|
||||
set_provider_fn(provider)
|
||||
except Exception as e:
|
||||
|
|
@ -274,7 +293,9 @@ class OpenTelemetry(CustomLogger):
|
|||
from opentelemetry.trace import SpanKind
|
||||
|
||||
def create_tracer_provider():
|
||||
provider = TracerProvider(resource=self._get_litellm_resource(self.config))
|
||||
provider = TracerProvider(
|
||||
resource=self._get_litellm_resource(self.config)
|
||||
)
|
||||
provider.add_span_processor(self._get_span_processor())
|
||||
return provider
|
||||
|
||||
|
|
@ -388,10 +409,14 @@ class OpenTelemetry(CustomLogger):
|
|||
def log_failure_event(self, kwargs, response_obj, start_time, end_time):
|
||||
self._handle_failure(kwargs, response_obj, start_time, end_time)
|
||||
|
||||
async def async_log_success_event(self, kwargs, response_obj, start_time, end_time):
|
||||
async def async_log_success_event(
|
||||
self, kwargs, response_obj, start_time, end_time
|
||||
):
|
||||
self._handle_success(kwargs, response_obj, start_time, end_time)
|
||||
|
||||
async def async_log_failure_event(self, kwargs, response_obj, start_time, end_time):
|
||||
async def async_log_failure_event(
|
||||
self, kwargs, response_obj, start_time, end_time
|
||||
):
|
||||
self._handle_failure(kwargs, response_obj, start_time, end_time)
|
||||
|
||||
async def async_service_success_hook(
|
||||
|
|
@ -588,7 +613,9 @@ class OpenTelemetry(CustomLogger):
|
|||
|
||||
if dynamic_headers is not None:
|
||||
# Create spans using a temporary tracer with dynamic headers
|
||||
tracer_to_use = self._get_tracer_with_dynamic_headers(dynamic_headers)
|
||||
tracer_to_use = self._get_tracer_with_dynamic_headers(
|
||||
dynamic_headers
|
||||
)
|
||||
verbose_logger.debug(
|
||||
"Using dynamic headers for this request: %s", dynamic_headers
|
||||
)
|
||||
|
|
@ -624,7 +651,9 @@ class OpenTelemetry(CustomLogger):
|
|||
)
|
||||
|
||||
# Create a temporary tracer provider with dynamic headers
|
||||
temp_provider = TracerProvider(resource=self._get_litellm_resource(self.config))
|
||||
temp_provider = TracerProvider(
|
||||
resource=self._get_litellm_resource(self.config)
|
||||
)
|
||||
temp_provider.add_span_processor(
|
||||
self._get_span_processor(dynamic_headers=dynamic_headers)
|
||||
)
|
||||
|
|
@ -755,7 +784,9 @@ class OpenTelemetry(CustomLogger):
|
|||
metadata = litellm_params.get("metadata") or {}
|
||||
generation_name = metadata.get("generation_name")
|
||||
|
||||
raw_span_name = generation_name if generation_name else RAW_REQUEST_SPAN_NAME
|
||||
raw_span_name = (
|
||||
generation_name if generation_name else RAW_REQUEST_SPAN_NAME
|
||||
)
|
||||
|
||||
otel_tracer: Tracer = self.get_tracer_to_use_for_request(kwargs)
|
||||
raw_span = otel_tracer.start_span(
|
||||
|
|
@ -780,7 +811,9 @@ class OpenTelemetry(CustomLogger):
|
|||
}
|
||||
|
||||
std_log = kwargs.get("standard_logging_object")
|
||||
md = getattr(std_log, "metadata", None) or (std_log or {}).get("metadata", {})
|
||||
md = getattr(std_log, "metadata", None) or (std_log or {}).get(
|
||||
"metadata", {}
|
||||
)
|
||||
for key in [
|
||||
"user_api_key_hash",
|
||||
"user_api_key_alias",
|
||||
|
|
@ -802,9 +835,9 @@ class OpenTelemetry(CustomLogger):
|
|||
common_attrs[f"metadata.{key}"] = str(md[key])
|
||||
|
||||
# get hidden params
|
||||
hidden_params = getattr(std_log, "hidden_params", None) or (std_log or {}).get(
|
||||
"hidden_params", {}
|
||||
)
|
||||
hidden_params = getattr(std_log, "hidden_params", None) or (
|
||||
std_log or {}
|
||||
).get("hidden_params", {})
|
||||
if hidden_params:
|
||||
common_attrs["hidden_params"] = safe_dumps(hidden_params)
|
||||
|
||||
|
|
@ -838,7 +871,9 @@ class OpenTelemetry(CustomLogger):
|
|||
self._record_response_duration_metric(kwargs, end_time, common_attrs)
|
||||
|
||||
@staticmethod
|
||||
def _to_timestamp(val: Optional[Union[datetime, float, str]]) -> Optional[float]:
|
||||
def _to_timestamp(
|
||||
val: Optional[Union[datetime, float, str]],
|
||||
) -> Optional[float]:
|
||||
"""Convert datetime/float/string to timestamp."""
|
||||
if val is None:
|
||||
return None
|
||||
|
|
@ -855,7 +890,9 @@ class OpenTelemetry(CustomLogger):
|
|||
except ValueError:
|
||||
return None
|
||||
|
||||
def _record_time_to_first_token_metric(self, kwargs: dict, common_attrs: dict):
|
||||
def _record_time_to_first_token_metric(
|
||||
self, kwargs: dict, common_attrs: dict
|
||||
):
|
||||
"""Record Time to First Token (TTFT) metric for streaming requests."""
|
||||
optional_params = kwargs.get("optional_params", {})
|
||||
is_streaming = optional_params.get("stream", False)
|
||||
|
|
@ -868,7 +905,10 @@ class OpenTelemetry(CustomLogger):
|
|||
api_call_start_time = kwargs.get("api_call_start_time", None)
|
||||
completion_start_time = kwargs.get("completion_start_time", None)
|
||||
|
||||
if api_call_start_time is not None and completion_start_time is not None:
|
||||
if (
|
||||
api_call_start_time is not None
|
||||
and completion_start_time is not None
|
||||
):
|
||||
# Convert to timestamps if needed (handles datetime, float, and string)
|
||||
api_call_start_ts = self._to_timestamp(api_call_start_time)
|
||||
completion_start_ts = self._to_timestamp(completion_start_time)
|
||||
|
|
@ -876,7 +916,9 @@ class OpenTelemetry(CustomLogger):
|
|||
if api_call_start_ts is None or completion_start_ts is None:
|
||||
return # Skip recording if conversion failed
|
||||
|
||||
time_to_first_token_seconds = completion_start_ts - api_call_start_ts
|
||||
time_to_first_token_seconds = (
|
||||
completion_start_ts - api_call_start_ts
|
||||
)
|
||||
self._time_to_first_token_histogram.record(
|
||||
time_to_first_token_seconds, attributes=common_attrs
|
||||
)
|
||||
|
|
@ -946,7 +988,9 @@ class OpenTelemetry(CustomLogger):
|
|||
generation_time_seconds = duration_s
|
||||
|
||||
if generation_time_seconds > 0:
|
||||
time_per_output_token_seconds = generation_time_seconds / completion_tokens
|
||||
time_per_output_token_seconds = (
|
||||
generation_time_seconds / completion_tokens
|
||||
)
|
||||
self._time_per_output_token_histogram.record(
|
||||
time_per_output_token_seconds, attributes=common_attrs
|
||||
)
|
||||
|
|
@ -1007,21 +1051,26 @@ class OpenTelemetry(CustomLogger):
|
|||
# See: https://github.com/open-telemetry/opentelemetry-python/pull/4676
|
||||
# TODO: Refactor to use the proper OTEL Logs API instead of directly creating SDK LogRecords
|
||||
|
||||
from opentelemetry._logs import SeverityNumber, get_logger, get_logger_provider
|
||||
from opentelemetry._logs import (
|
||||
SeverityNumber,
|
||||
get_logger,
|
||||
)
|
||||
|
||||
try:
|
||||
from opentelemetry.sdk._logs import LogRecord as SdkLogRecord # type: ignore[attr-defined] # OTEL < 1.39.0
|
||||
except ImportError:
|
||||
from opentelemetry.sdk._logs._internal import LogRecord as SdkLogRecord # type: ignore[attr-defined, no-redef] # OTEL >= 1.39.0
|
||||
# MyPy evaluates both branches of try/except imports and can fail when
|
||||
# newer OTEL stubs remove/relocate symbols. Gate the typing import so
|
||||
# only the canonical location is type-checked.
|
||||
if TYPE_CHECKING:
|
||||
from opentelemetry.sdk._logs._internal import LogRecord as SdkLogRecord
|
||||
else:
|
||||
try:
|
||||
from opentelemetry.sdk._logs import (
|
||||
LogRecord as SdkLogRecord, # type: ignore[attr-defined]
|
||||
)
|
||||
except ImportError:
|
||||
from opentelemetry.sdk._logs._internal import LogRecord as SdkLogRecord
|
||||
|
||||
otel_logger = get_logger(LITELLM_LOGGER_NAME)
|
||||
|
||||
# Get the resource from the logger provider
|
||||
logger_provider = get_logger_provider()
|
||||
resource = getattr(
|
||||
logger_provider, "_resource", None
|
||||
) or self._get_litellm_resource(self.config)
|
||||
|
||||
parent_ctx = span.get_span_context()
|
||||
provider = (kwargs.get("litellm_params") or {}).get(
|
||||
"custom_llm_provider", "Unknown"
|
||||
|
|
@ -1030,7 +1079,10 @@ class OpenTelemetry(CustomLogger):
|
|||
# per-message events
|
||||
for msg in kwargs.get("messages", []):
|
||||
role = msg.get("role", "user")
|
||||
attrs = {"event_name": "gen_ai.content.prompt", "gen_ai.system": provider}
|
||||
attrs = {
|
||||
"event_name": "gen_ai.content.prompt",
|
||||
"gen_ai.system": provider,
|
||||
}
|
||||
if role == "tool" and msg.get("id"):
|
||||
attrs["id"] = msg["id"]
|
||||
if self.message_logging and msg.get("content"):
|
||||
|
|
@ -1044,7 +1096,6 @@ class OpenTelemetry(CustomLogger):
|
|||
severity_number=SeverityNumber.INFO,
|
||||
severity_text="INFO",
|
||||
body=msg.copy(),
|
||||
resource=resource,
|
||||
attributes=attrs,
|
||||
)
|
||||
otel_logger.emit(log_record)
|
||||
|
|
@ -1076,7 +1127,6 @@ class OpenTelemetry(CustomLogger):
|
|||
severity_number=SeverityNumber.INFO,
|
||||
severity_text="INFO",
|
||||
body=body,
|
||||
resource=resource,
|
||||
attributes=attrs,
|
||||
)
|
||||
otel_logger.emit(log_record)
|
||||
|
|
@ -1146,7 +1196,9 @@ class OpenTelemetry(CustomLogger):
|
|||
value=guardrail_information.get("guardrail_mode"),
|
||||
)
|
||||
|
||||
masked_entity_count = guardrail_information.get("masked_entity_count")
|
||||
masked_entity_count = guardrail_information.get(
|
||||
"masked_entity_count"
|
||||
)
|
||||
if masked_entity_count is not None:
|
||||
guardrail_span.set_attribute(
|
||||
"masked_entity_count", safe_dumps(masked_entity_count)
|
||||
|
|
@ -1173,8 +1225,9 @@ class OpenTelemetry(CustomLogger):
|
|||
# Decide whether to create a primary span
|
||||
# Always create if no parent span exists (backward compatibility)
|
||||
# OR if USE_OTEL_LITELLM_REQUEST_SPAN is explicitly enabled
|
||||
should_create_primary_span = parent_otel_span is None or get_secret_bool(
|
||||
"USE_OTEL_LITELLM_REQUEST_SPAN"
|
||||
should_create_primary_span = (
|
||||
parent_otel_span is None
|
||||
or get_secret_bool("USE_OTEL_LITELLM_REQUEST_SPAN")
|
||||
)
|
||||
|
||||
if should_create_primary_span:
|
||||
|
|
@ -1200,7 +1253,9 @@ class OpenTelemetry(CustomLogger):
|
|||
if parent_otel_span.is_recording():
|
||||
parent_otel_span.set_status(Status(StatusCode.ERROR))
|
||||
self.set_attributes(parent_otel_span, kwargs, response_obj)
|
||||
self._record_exception_on_span(span=parent_otel_span, kwargs=kwargs)
|
||||
self._record_exception_on_span(
|
||||
span=parent_otel_span, kwargs=kwargs
|
||||
)
|
||||
|
||||
# Create span for guardrail information
|
||||
self._create_guardrail_span(kwargs=kwargs, context=_parent_context)
|
||||
|
|
@ -1223,7 +1278,9 @@ class OpenTelemetry(CustomLogger):
|
|||
2. Sets structured error attributes from StandardLoggingPayloadErrorInformation
|
||||
"""
|
||||
try:
|
||||
from litellm.integrations._types.open_inference import ErrorAttributes
|
||||
from litellm.integrations._types.open_inference import (
|
||||
ErrorAttributes,
|
||||
)
|
||||
|
||||
# Get the exception object if available
|
||||
exception = kwargs.get("exception")
|
||||
|
|
@ -1233,15 +1290,17 @@ class OpenTelemetry(CustomLogger):
|
|||
span.record_exception(exception)
|
||||
|
||||
# Get StandardLoggingPayload for structured error information
|
||||
standard_logging_payload: Optional[StandardLoggingPayload] = kwargs.get(
|
||||
"standard_logging_object"
|
||||
standard_logging_payload: Optional[StandardLoggingPayload] = (
|
||||
kwargs.get("standard_logging_object")
|
||||
)
|
||||
|
||||
if standard_logging_payload is None:
|
||||
return
|
||||
|
||||
# Extract error_information from StandardLoggingPayload
|
||||
error_information = standard_logging_payload.get("error_information")
|
||||
error_information = standard_logging_payload.get(
|
||||
"error_information"
|
||||
)
|
||||
|
||||
if error_information is None:
|
||||
# Fallback to error_str if error_information is not available
|
||||
|
|
@ -1331,7 +1390,9 @@ class OpenTelemetry(CustomLogger):
|
|||
)
|
||||
pass
|
||||
|
||||
def cast_as_primitive_value_type(self, value) -> Union[str, bool, int, float]:
|
||||
def cast_as_primitive_value_type(
|
||||
self, value
|
||||
) -> Union[str, bool, int, float]:
|
||||
"""
|
||||
Casts the value to a primitive OTEL type if it is not already a primitive type.
|
||||
|
||||
|
|
@ -1401,8 +1462,8 @@ class OpenTelemetry(CustomLogger):
|
|||
|
||||
optional_params = kwargs.get("optional_params", {})
|
||||
litellm_params = kwargs.get("litellm_params", {}) or {}
|
||||
standard_logging_payload: Optional[StandardLoggingPayload] = kwargs.get(
|
||||
"standard_logging_object"
|
||||
standard_logging_payload: Optional[StandardLoggingPayload] = (
|
||||
kwargs.get("standard_logging_object")
|
||||
)
|
||||
if standard_logging_payload is None:
|
||||
raise ValueError("standard_logging_object not found in kwargs")
|
||||
|
|
@ -1424,11 +1485,13 @@ class OpenTelemetry(CustomLogger):
|
|||
) or (standard_logging_payload or {}).get("hidden_params", {})
|
||||
if hidden_params:
|
||||
self.safe_set_attribute(
|
||||
span=span, key="hidden_params", value=safe_dumps(hidden_params)
|
||||
span=span,
|
||||
key="hidden_params",
|
||||
value=safe_dumps(hidden_params),
|
||||
)
|
||||
# Cost breakdown tracking
|
||||
cost_breakdown: Optional[CostBreakdown] = standard_logging_payload.get(
|
||||
"cost_breakdown"
|
||||
cost_breakdown: Optional[CostBreakdown] = (
|
||||
standard_logging_payload.get("cost_breakdown")
|
||||
)
|
||||
if cost_breakdown:
|
||||
for key, value in cost_breakdown.items():
|
||||
|
|
@ -1504,7 +1567,9 @@ class OpenTelemetry(CustomLogger):
|
|||
# The unique identifier for the completion.
|
||||
if response_obj and response_obj.get("id"):
|
||||
self.safe_set_attribute(
|
||||
span=span, key="gen_ai.response.id", value=response_obj.get("id")
|
||||
span=span,
|
||||
key="gen_ai.response.id",
|
||||
value=response_obj.get("id"),
|
||||
)
|
||||
|
||||
# The model used to generate the response.
|
||||
|
|
@ -1639,7 +1704,9 @@ class OpenTelemetry(CustomLogger):
|
|||
"OpenTelemetry logging error in set_attributes %s", str(e)
|
||||
)
|
||||
|
||||
def _cast_as_primitive_value_type(self, value) -> Union[str, bool, int, float]:
|
||||
def _cast_as_primitive_value_type(
|
||||
self, value
|
||||
) -> Union[str, bool, int, float]:
|
||||
"""
|
||||
Casts the value to a primitive OTEL type if it is not already a primitive type.
|
||||
|
||||
|
|
@ -1673,7 +1740,10 @@ class OpenTelemetry(CustomLogger):
|
|||
if isinstance(messages, str):
|
||||
# Handle system_instructions passed as a string
|
||||
return [
|
||||
{"role": "system", "parts": [{"type": "text", "content": messages}]}
|
||||
{
|
||||
"role": "system",
|
||||
"parts": [{"type": "text", "content": messages}],
|
||||
}
|
||||
]
|
||||
|
||||
transformed = []
|
||||
|
|
@ -1714,9 +1784,11 @@ class OpenTelemetry(CustomLogger):
|
|||
message = choice.get("message") or {}
|
||||
finish_reason = choice.get("finish_reason")
|
||||
|
||||
transformed_msg = self._transform_messages_to_otel_semantic_conventions(
|
||||
[message]
|
||||
)[0]
|
||||
transformed_msg = (
|
||||
self._transform_messages_to_otel_semantic_conventions(
|
||||
[message]
|
||||
)[0]
|
||||
)
|
||||
if finish_reason:
|
||||
transformed_msg["finish_reason"] = finish_reason
|
||||
|
||||
|
|
@ -1728,7 +1800,9 @@ class OpenTelemetry(CustomLogger):
|
|||
self.set_attributes(span, kwargs, response_obj)
|
||||
kwargs.get("optional_params", {})
|
||||
litellm_params = kwargs.get("litellm_params", {}) or {}
|
||||
custom_llm_provider = litellm_params.get("custom_llm_provider", "Unknown")
|
||||
custom_llm_provider = litellm_params.get(
|
||||
"custom_llm_provider", "Unknown"
|
||||
)
|
||||
|
||||
_raw_response = kwargs.get("original_response")
|
||||
_additional_args = kwargs.get("additional_args", {}) or {}
|
||||
|
|
@ -1741,7 +1815,9 @@ class OpenTelemetry(CustomLogger):
|
|||
if complete_input_dict and isinstance(complete_input_dict, dict):
|
||||
for param, val in complete_input_dict.items():
|
||||
self.safe_set_attribute(
|
||||
span=span, key=f"llm.{custom_llm_provider}.{param}", value=val
|
||||
span=span,
|
||||
key=f"llm.{custom_llm_provider}.{param}",
|
||||
value=val,
|
||||
)
|
||||
|
||||
#############################################
|
||||
|
|
@ -1773,7 +1849,8 @@ class OpenTelemetry(CustomLogger):
|
|||
)
|
||||
except Exception as e:
|
||||
verbose_logger.exception(
|
||||
"OpenTelemetry logging error in set_raw_request_attributes %s", str(e)
|
||||
"OpenTelemetry logging error in set_raw_request_attributes %s",
|
||||
str(e),
|
||||
)
|
||||
|
||||
def _to_ns(self, dt):
|
||||
|
|
@ -1813,7 +1890,9 @@ class OpenTelemetry(CustomLogger):
|
|||
)
|
||||
|
||||
litellm_params = kwargs.get("litellm_params", {}) or {}
|
||||
proxy_server_request = litellm_params.get("proxy_server_request", {}) or {}
|
||||
proxy_server_request = (
|
||||
litellm_params.get("proxy_server_request", {}) or {}
|
||||
)
|
||||
headers = proxy_server_request.get("headers", {}) or {}
|
||||
traceparent = headers.get("traceparent", None)
|
||||
_metadata = litellm_params.get("metadata", {}) or {}
|
||||
|
|
@ -1832,7 +1911,10 @@ class OpenTelemetry(CustomLogger):
|
|||
"OpenTelemetry: Using traceparent header for context propagation"
|
||||
)
|
||||
carrier = {"traceparent": traceparent}
|
||||
return TraceContextTextMapPropagator().extract(carrier=carrier), None
|
||||
return (
|
||||
TraceContextTextMapPropagator().extract(carrier=carrier),
|
||||
None,
|
||||
)
|
||||
|
||||
# Priority 3: Active span from global context (auto-detection)
|
||||
try:
|
||||
|
|
@ -1960,10 +2042,14 @@ class OpenTelemetry(CustomLogger):
|
|||
self.OTEL_HEADERS,
|
||||
)
|
||||
|
||||
_split_otel_headers = OpenTelemetry._get_headers_dictionary(self.OTEL_HEADERS)
|
||||
_split_otel_headers = OpenTelemetry._get_headers_dictionary(
|
||||
self.OTEL_HEADERS
|
||||
)
|
||||
|
||||
# Normalize endpoint for logs - ensure it points to /v1/logs instead of /v1/traces
|
||||
normalized_endpoint = self._normalize_otel_endpoint(self.OTEL_ENDPOINT, "logs")
|
||||
normalized_endpoint = self._normalize_otel_endpoint(
|
||||
self.OTEL_ENDPOINT, "logs"
|
||||
)
|
||||
|
||||
verbose_logger.debug(
|
||||
"OpenTelemetry: Log endpoint normalized from %s to %s",
|
||||
|
|
@ -2051,14 +2137,18 @@ class OpenTelemetry(CustomLogger):
|
|||
self.OTEL_HEADERS,
|
||||
)
|
||||
|
||||
_split_otel_headers = OpenTelemetry._get_headers_dictionary(self.OTEL_HEADERS)
|
||||
_split_otel_headers = OpenTelemetry._get_headers_dictionary(
|
||||
self.OTEL_HEADERS
|
||||
)
|
||||
normalized_endpoint = self._normalize_otel_endpoint(
|
||||
self.OTEL_ENDPOINT, "metrics"
|
||||
)
|
||||
|
||||
if self.OTEL_EXPORTER == "console":
|
||||
exporter = ConsoleMetricExporter()
|
||||
return PeriodicExportingMetricReader(exporter, export_interval_millis=5000)
|
||||
return PeriodicExportingMetricReader(
|
||||
exporter, export_interval_millis=5000
|
||||
)
|
||||
|
||||
elif (
|
||||
self.OTEL_EXPORTER == "otlp_http"
|
||||
|
|
@ -2074,7 +2164,9 @@ class OpenTelemetry(CustomLogger):
|
|||
headers=_split_otel_headers,
|
||||
preferred_temporality={Histogram: AggregationTemporality.DELTA},
|
||||
)
|
||||
return PeriodicExportingMetricReader(exporter, export_interval_millis=5000)
|
||||
return PeriodicExportingMetricReader(
|
||||
exporter, export_interval_millis=5000
|
||||
)
|
||||
|
||||
elif self.OTEL_EXPORTER == "otlp_grpc" or self.OTEL_EXPORTER == "grpc":
|
||||
try:
|
||||
|
|
@ -2092,7 +2184,9 @@ class OpenTelemetry(CustomLogger):
|
|||
headers=_split_otel_headers,
|
||||
preferred_temporality={Histogram: AggregationTemporality.DELTA},
|
||||
)
|
||||
return PeriodicExportingMetricReader(exporter, export_interval_millis=5000)
|
||||
return PeriodicExportingMetricReader(
|
||||
exporter, export_interval_millis=5000
|
||||
)
|
||||
|
||||
else:
|
||||
verbose_logger.warning(
|
||||
|
|
@ -2100,7 +2194,9 @@ class OpenTelemetry(CustomLogger):
|
|||
self.OTEL_EXPORTER,
|
||||
)
|
||||
exporter = ConsoleMetricExporter()
|
||||
return PeriodicExportingMetricReader(exporter, export_interval_millis=5000)
|
||||
return PeriodicExportingMetricReader(
|
||||
exporter, export_interval_millis=5000
|
||||
)
|
||||
|
||||
def _normalize_otel_endpoint(
|
||||
self, endpoint: Optional[str], signal_type: str
|
||||
|
|
@ -2171,7 +2267,9 @@ class OpenTelemetry(CustomLogger):
|
|||
return endpoint
|
||||
|
||||
@staticmethod
|
||||
def _get_headers_dictionary(headers: Optional[Union[str, dict]]) -> Dict[str, str]:
|
||||
def _get_headers_dictionary(
|
||||
headers: Optional[Union[str, dict]],
|
||||
) -> Dict[str, str]:
|
||||
"""
|
||||
Convert a string or dictionary of headers into a dictionary of headers.
|
||||
"""
|
||||
|
|
|
|||
|
|
@ -8,40 +8,187 @@ export LITELLM_LOCAL_MODEL_COST_MAP=True
|
|||
```
|
||||
"""
|
||||
|
||||
import json
|
||||
import os
|
||||
from importlib.resources import files
|
||||
|
||||
import httpx
|
||||
|
||||
from litellm import verbose_logger
|
||||
from litellm.constants import (
|
||||
MODEL_COST_MAP_MAX_SHRINK_RATIO,
|
||||
MODEL_COST_MAP_MIN_MODEL_COUNT,
|
||||
)
|
||||
|
||||
|
||||
class GetModelCostMap:
|
||||
"""
|
||||
Handles fetching, validating, and loading the model cost map.
|
||||
|
||||
Only the backup model *count* is cached (a single int). The full
|
||||
backup dict is never held in memory — it is only parsed when it
|
||||
needs to be *returned* as a fallback.
|
||||
"""
|
||||
|
||||
_backup_model_count: int = -1 # -1 = not yet loaded
|
||||
|
||||
@staticmethod
|
||||
def load_local_model_cost_map() -> dict:
|
||||
"""Load the local backup model cost map bundled with the package."""
|
||||
content = json.loads(
|
||||
files("litellm")
|
||||
.joinpath("model_prices_and_context_window_backup.json")
|
||||
.read_text(encoding="utf-8")
|
||||
)
|
||||
return content
|
||||
|
||||
@classmethod
|
||||
def _get_backup_model_count(cls) -> int:
|
||||
"""Return the number of models in the local backup (cached int)."""
|
||||
if cls._backup_model_count < 0:
|
||||
backup = cls.load_local_model_cost_map()
|
||||
cls._backup_model_count = len(backup)
|
||||
return cls._backup_model_count
|
||||
|
||||
@staticmethod
|
||||
def _check_is_valid_dict(fetched_map: dict) -> bool:
|
||||
"""Check 1: fetched map is a non-empty dict."""
|
||||
if not isinstance(fetched_map, dict):
|
||||
verbose_logger.warning(
|
||||
"LiteLLM: Fetched model cost map is not a dict (type=%s). "
|
||||
"Falling back to local backup.",
|
||||
type(fetched_map).__name__,
|
||||
)
|
||||
return False
|
||||
|
||||
if len(fetched_map) == 0:
|
||||
verbose_logger.warning(
|
||||
"LiteLLM: Fetched model cost map is empty. "
|
||||
"Falling back to local backup.",
|
||||
)
|
||||
return False
|
||||
|
||||
return True
|
||||
|
||||
@classmethod
|
||||
def _check_model_count_not_reduced(
|
||||
cls,
|
||||
fetched_map: dict,
|
||||
backup_model_count: int,
|
||||
min_model_count: int = MODEL_COST_MAP_MIN_MODEL_COUNT,
|
||||
max_shrink_ratio: float = MODEL_COST_MAP_MAX_SHRINK_RATIO,
|
||||
) -> bool:
|
||||
"""Check 2: model count has not reduced significantly vs backup."""
|
||||
fetched_count = len(fetched_map)
|
||||
|
||||
if fetched_count < min_model_count:
|
||||
verbose_logger.warning(
|
||||
"LiteLLM: Fetched model cost map has only %d models (minimum=%d). "
|
||||
"This may indicate a corrupted upstream file. "
|
||||
"Falling back to local backup.",
|
||||
fetched_count,
|
||||
min_model_count,
|
||||
)
|
||||
return False
|
||||
|
||||
if backup_model_count > 0 and fetched_count < backup_model_count * max_shrink_ratio:
|
||||
verbose_logger.warning(
|
||||
"LiteLLM: Fetched model cost map shrank significantly "
|
||||
"(fetched=%d, backup=%d, threshold=%.0f%%). "
|
||||
"This may indicate a corrupted upstream file. "
|
||||
"Falling back to local backup.",
|
||||
fetched_count,
|
||||
backup_model_count,
|
||||
max_shrink_ratio * 100,
|
||||
)
|
||||
return False
|
||||
|
||||
return True
|
||||
|
||||
@classmethod
|
||||
def validate_model_cost_map(
|
||||
cls,
|
||||
fetched_map: dict,
|
||||
backup_model_count: int,
|
||||
min_model_count: int = MODEL_COST_MAP_MIN_MODEL_COUNT,
|
||||
max_shrink_ratio: float = MODEL_COST_MAP_MAX_SHRINK_RATIO,
|
||||
) -> bool:
|
||||
"""
|
||||
Validate the integrity of a fetched model cost map.
|
||||
|
||||
Runs each check in order and returns False on the first failure.
|
||||
|
||||
Checks:
|
||||
1. ``_check_is_valid_dict`` -- fetched map is a non-empty dict.
|
||||
2. ``_check_model_count_not_reduced`` -- model count meets minimum
|
||||
and has not shrunk >``max_shrink_ratio`` vs backup.
|
||||
|
||||
Returns True if all checks pass, False otherwise.
|
||||
"""
|
||||
if not cls._check_is_valid_dict(fetched_map):
|
||||
return False
|
||||
|
||||
if not cls._check_model_count_not_reduced(
|
||||
fetched_map=fetched_map,
|
||||
backup_model_count=backup_model_count,
|
||||
min_model_count=min_model_count,
|
||||
max_shrink_ratio=max_shrink_ratio,
|
||||
):
|
||||
return False
|
||||
|
||||
return True
|
||||
|
||||
@staticmethod
|
||||
def fetch_remote_model_cost_map(url: str, timeout: int = 5) -> dict:
|
||||
"""
|
||||
Fetch the model cost map from a remote URL.
|
||||
|
||||
Returns the parsed JSON dict. Raises on network/parse errors
|
||||
(caller is expected to handle).
|
||||
"""
|
||||
response = httpx.get(url, timeout=timeout)
|
||||
response.raise_for_status()
|
||||
return response.json()
|
||||
|
||||
|
||||
def get_model_cost_map(url: str) -> dict:
|
||||
if (
|
||||
os.getenv("LITELLM_LOCAL_MODEL_COST_MAP", False)
|
||||
or os.getenv("LITELLM_LOCAL_MODEL_COST_MAP", False) == "True"
|
||||
):
|
||||
from importlib.resources import files
|
||||
import json
|
||||
"""
|
||||
Public entry point — returns the model cost map dict.
|
||||
|
||||
content = json.loads(
|
||||
files("litellm")
|
||||
.joinpath("model_prices_and_context_window_backup.json")
|
||||
.read_text(encoding="utf-8")
|
||||
)
|
||||
return content
|
||||
1. If ``LITELLM_LOCAL_MODEL_COST_MAP`` is set, uses the local backup only.
|
||||
2. Otherwise fetches from ``url``, validates integrity, and falls back
|
||||
to the local backup on any failure.
|
||||
|
||||
Only the backup model count is cached (a single int) for validation.
|
||||
The full backup dict is only parsed when it must be *returned* as a
|
||||
fallback — it is never held in memory long-term.
|
||||
"""
|
||||
# Note: can't use get_secret_bool here — this runs during litellm.__init__
|
||||
# before litellm._key_management_settings is set.
|
||||
if os.getenv("LITELLM_LOCAL_MODEL_COST_MAP", "").lower() == "true":
|
||||
return GetModelCostMap.load_local_model_cost_map()
|
||||
|
||||
try:
|
||||
response = httpx.get(
|
||||
url, timeout=5
|
||||
) # set a 5 second timeout for the get request
|
||||
response.raise_for_status() # Raise an exception if the request is unsuccessful
|
||||
content = response.json()
|
||||
return content
|
||||
except Exception:
|
||||
from importlib.resources import files
|
||||
import json
|
||||
|
||||
content = json.loads(
|
||||
files("litellm")
|
||||
.joinpath("model_prices_and_context_window_backup.json")
|
||||
.read_text(encoding="utf-8")
|
||||
content = GetModelCostMap.fetch_remote_model_cost_map(url)
|
||||
except Exception as e:
|
||||
verbose_logger.warning(
|
||||
"LiteLLM: Failed to fetch remote model cost map from %s: %s. "
|
||||
"Falling back to local backup.",
|
||||
url,
|
||||
str(e),
|
||||
)
|
||||
return content
|
||||
return GetModelCostMap.load_local_model_cost_map()
|
||||
|
||||
# Validate using cached count (cheap int comparison, no file I/O)
|
||||
if not GetModelCostMap.validate_model_cost_map(
|
||||
fetched_map=content,
|
||||
backup_model_count=GetModelCostMap._get_backup_model_count(),
|
||||
):
|
||||
verbose_logger.warning(
|
||||
"LiteLLM: Fetched model cost map failed integrity check. "
|
||||
"Using local backup instead. url=%s",
|
||||
url,
|
||||
)
|
||||
return GetModelCostMap.load_local_model_cost_map()
|
||||
|
||||
return content
|
||||
|
|
|
|||
|
|
@ -1272,3 +1272,59 @@ def parse_tool_call_arguments(
|
|||
)
|
||||
|
||||
raise ValueError(error_message) from e
|
||||
|
||||
|
||||
def split_concatenated_json_objects(raw: str) -> List[Dict[str, Any]]:
|
||||
"""
|
||||
Split a string that contains one or more concatenated JSON objects into
|
||||
a list of parsed dicts.
|
||||
|
||||
LLM providers (notably Bedrock Claude Sonnet 4.5) sometimes return
|
||||
multiple tool-call argument objects concatenated in a single
|
||||
``arguments`` string, e.g.::
|
||||
|
||||
'{"command":["curl",...]}{"command":["curl",...]}{"command":["curl",...]}'
|
||||
|
||||
``json.loads()`` fails on this with ``JSONDecodeError: Extra data``.
|
||||
This helper uses ``json.JSONDecoder.raw_decode()`` to walk the string
|
||||
and extract each JSON object individually.
|
||||
|
||||
Returns
|
||||
-------
|
||||
list[dict]
|
||||
A list of parsed dicts – one per JSON object found. If *raw* is
|
||||
empty or whitespace-only, an empty list is returned.
|
||||
|
||||
Raises
|
||||
------
|
||||
json.JSONDecodeError
|
||||
If the string contains text that cannot be parsed as JSON at all.
|
||||
"""
|
||||
import json
|
||||
|
||||
raw = raw.strip()
|
||||
if not raw:
|
||||
return []
|
||||
|
||||
decoder = json.JSONDecoder()
|
||||
results: List[Dict[str, Any]] = []
|
||||
idx = 0
|
||||
length = len(raw)
|
||||
|
||||
while idx < length:
|
||||
# Skip whitespace between objects
|
||||
while idx < length and raw[idx] in " \t\n\r":
|
||||
idx += 1
|
||||
if idx >= length:
|
||||
break
|
||||
|
||||
obj, end_idx = decoder.raw_decode(raw, idx)
|
||||
if isinstance(obj, dict):
|
||||
results.append(obj)
|
||||
else:
|
||||
# Non-dict JSON value – wrap in empty dict (Bedrock requires
|
||||
# toolUse.input to be an object).
|
||||
results.append({})
|
||||
idx = end_idx
|
||||
|
||||
return results
|
||||
|
|
|
|||
|
|
@ -3287,25 +3287,68 @@ def _convert_to_bedrock_tool_call_invoke(
|
|||
- extract name
|
||||
- extract id
|
||||
"""
|
||||
from litellm.litellm_core_utils.prompt_templates.common_utils import (
|
||||
split_concatenated_json_objects,
|
||||
)
|
||||
|
||||
try:
|
||||
_parts_list: List[BedrockContentBlock] = []
|
||||
for tool in tool_calls:
|
||||
if "function" in tool:
|
||||
id = tool["id"]
|
||||
tool_id = tool["id"]
|
||||
name = tool["function"].get("name", "")
|
||||
arguments = tool["function"].get("arguments", "")
|
||||
arguments_dict = json.loads(arguments) if arguments else {}
|
||||
# Ensure arguments_dict is always a dict (Bedrock requires toolUse.input to be an object)
|
||||
# When some providers return arguments: '""' (JSON-encoded empty string), json.loads returns ""
|
||||
if not isinstance(arguments_dict, dict):
|
||||
arguments_dict = {}
|
||||
|
||||
if not arguments or not arguments.strip():
|
||||
arguments_dict = {}
|
||||
else:
|
||||
arguments_dict = json.loads(arguments)
|
||||
try:
|
||||
arguments_dict = json.loads(arguments)
|
||||
# Ensure arguments_dict is always a dict
|
||||
# (Bedrock requires toolUse.input to be an object).
|
||||
# Some providers return arguments: '""' which
|
||||
# json.loads decodes to a bare string.
|
||||
if not isinstance(arguments_dict, dict):
|
||||
arguments_dict = {}
|
||||
except json.JSONDecodeError:
|
||||
# The model may return multiple JSON objects
|
||||
# concatenated in a single arguments string, e.g.
|
||||
# '{"cmd":"a"}{"cmd":"b"}{"cmd":"c"}'
|
||||
# Split them and emit one toolUse block per object.
|
||||
# Fixes: https://github.com/BerriAI/litellm/issues/20543
|
||||
parsed_objects = split_concatenated_json_objects(
|
||||
arguments
|
||||
)
|
||||
if parsed_objects:
|
||||
# First object keeps the original tool id.
|
||||
for obj_idx, obj in enumerate(parsed_objects):
|
||||
block_id = (
|
||||
tool_id
|
||||
if obj_idx == 0
|
||||
else f"{tool_id}_{obj_idx}"
|
||||
)
|
||||
bedrock_tool = BedrockToolUseBlock(
|
||||
input=obj, name=name, toolUseId=block_id
|
||||
)
|
||||
_parts_list.append(
|
||||
BedrockContentBlock(toolUse=bedrock_tool)
|
||||
)
|
||||
# cache_control applies to the whole original
|
||||
# tool call; attach after the last split block.
|
||||
if tool.get("cache_control", None) is not None:
|
||||
_parts_list.append(
|
||||
BedrockContentBlock(
|
||||
cachePoint=CachePointBlock(
|
||||
type="default"
|
||||
)
|
||||
)
|
||||
)
|
||||
continue
|
||||
# Fallback: no objects extracted — use empty dict.
|
||||
arguments_dict = {}
|
||||
|
||||
bedrock_tool = BedrockToolUseBlock(
|
||||
input=arguments_dict, name=name, toolUseId=id
|
||||
input=arguments_dict, name=name, toolUseId=tool_id
|
||||
)
|
||||
bedrock_content_block = BedrockContentBlock(toolUse=bedrock_tool)
|
||||
_parts_list.append(bedrock_content_block)
|
||||
|
|
|
|||
|
|
@ -30,6 +30,58 @@ ANTHROPIC_ADAPTER = AnthropicAdapter()
|
|||
|
||||
|
||||
class LiteLLMMessagesToCompletionTransformationHandler:
|
||||
@staticmethod
|
||||
def _route_openai_thinking_to_responses_api_if_needed(
|
||||
completion_kwargs: Dict[str, Any],
|
||||
*,
|
||||
thinking: Optional[Dict[str, Any]],
|
||||
) -> None:
|
||||
"""
|
||||
When users call `litellm.anthropic.messages.*` with a non-Anthropic model and
|
||||
`thinking={"type": "enabled", ...}`, LiteLLM converts this into OpenAI
|
||||
`reasoning_effort`.
|
||||
|
||||
For OpenAI models, Chat Completions typically does not return reasoning text
|
||||
(only token accounting). To return a thinking-like content block in the
|
||||
Anthropic response format, we route the request through OpenAI's Responses API
|
||||
and request a reasoning summary.
|
||||
"""
|
||||
custom_llm_provider = completion_kwargs.get("custom_llm_provider")
|
||||
if custom_llm_provider is None:
|
||||
try:
|
||||
_, inferred_provider, _, _ = litellm.utils.get_llm_provider(
|
||||
model=cast(str, completion_kwargs.get("model"))
|
||||
)
|
||||
custom_llm_provider = inferred_provider
|
||||
except Exception:
|
||||
custom_llm_provider = None
|
||||
|
||||
if custom_llm_provider != "openai":
|
||||
return
|
||||
|
||||
if not isinstance(thinking, dict) or thinking.get("type") != "enabled":
|
||||
return
|
||||
|
||||
model = completion_kwargs.get("model")
|
||||
if isinstance(model, str) and model and not model.startswith("responses/"):
|
||||
# Prefix model with "responses/" to route to OpenAI Responses API
|
||||
completion_kwargs["model"] = f"responses/{model}"
|
||||
|
||||
reasoning_effort = completion_kwargs.get("reasoning_effort")
|
||||
if isinstance(reasoning_effort, str) and reasoning_effort:
|
||||
completion_kwargs["reasoning_effort"] = {
|
||||
"effort": reasoning_effort,
|
||||
"summary": "detailed",
|
||||
}
|
||||
elif isinstance(reasoning_effort, dict):
|
||||
if (
|
||||
"summary" not in reasoning_effort
|
||||
and "generate_summary" not in reasoning_effort
|
||||
):
|
||||
updated_reasoning_effort = dict(reasoning_effort)
|
||||
updated_reasoning_effort["summary"] = "detailed"
|
||||
completion_kwargs["reasoning_effort"] = updated_reasoning_effort
|
||||
|
||||
@staticmethod
|
||||
def _prepare_completion_kwargs(
|
||||
*,
|
||||
|
|
@ -123,6 +175,11 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
):
|
||||
completion_kwargs[key] = value
|
||||
|
||||
LiteLLMMessagesToCompletionTransformationHandler._route_openai_thinking_to_responses_api_if_needed(
|
||||
completion_kwargs,
|
||||
thinking=thinking,
|
||||
)
|
||||
|
||||
return completion_kwargs, tool_name_mapping
|
||||
|
||||
@staticmethod
|
||||
|
|
|
|||
|
|
@ -1,6 +1,7 @@
|
|||
import asyncio
|
||||
import contextlib
|
||||
import os
|
||||
import ssl
|
||||
import typing
|
||||
import urllib.request
|
||||
from typing import Callable, Dict, Optional, Union
|
||||
|
|
@ -139,8 +140,13 @@ class LiteLLMAiohttpTransport(AiohttpTransport):
|
|||
Credit to: https://github.com/karpetrosyan/httpx-aiohttp for this implementation
|
||||
"""
|
||||
|
||||
def __init__(self, client: Union[ClientSession, Callable[[], ClientSession]]):
|
||||
def __init__(
|
||||
self,
|
||||
client: Union[ClientSession, Callable[[], ClientSession]],
|
||||
ssl_verify: Optional[Union[bool, ssl.SSLContext]] = None,
|
||||
):
|
||||
self.client = client
|
||||
self._ssl_verify = ssl_verify # Store for per-request SSL override
|
||||
super().__init__(client=client)
|
||||
# Store the client factory for recreating sessions when needed
|
||||
if callable(client):
|
||||
|
|
@ -214,6 +220,7 @@ class LiteLLMAiohttpTransport(AiohttpTransport):
|
|||
timeout: dict,
|
||||
proxy: Optional[str],
|
||||
sni_hostname: Optional[str],
|
||||
ssl_verify: Optional[Union[bool, ssl.SSLContext]] = None,
|
||||
) -> ClientResponse:
|
||||
"""
|
||||
Helper function to make an aiohttp request with the given parameters.
|
||||
|
|
@ -224,6 +231,7 @@ class LiteLLMAiohttpTransport(AiohttpTransport):
|
|||
timeout: Timeout settings dict with 'connect', 'read', 'pool' keys
|
||||
proxy: Optional proxy URL
|
||||
sni_hostname: Optional SNI hostname for SSL
|
||||
ssl_verify: Optional SSL verification setting (False to disable, SSLContext for custom)
|
||||
|
||||
Returns:
|
||||
ClientResponse from aiohttp
|
||||
|
|
@ -237,6 +245,13 @@ class LiteLLMAiohttpTransport(AiohttpTransport):
|
|||
data = request.stream # type: ignore
|
||||
request.headers.pop("transfer-encoding", None) # handled by aiohttp
|
||||
|
||||
# Only pass ssl kwarg when explicitly configured, to avoid
|
||||
# overriding the session/connector defaults with None (which is
|
||||
# not a valid value for aiohttp's ssl parameter).
|
||||
ssl_kwargs: Dict[str, Union[bool, ssl.SSLContext]] = {}
|
||||
if ssl_verify is not None:
|
||||
ssl_kwargs["ssl"] = ssl_verify
|
||||
|
||||
response = await client_session.request(
|
||||
method=request.method,
|
||||
url=YarlURL(str(request.url), encoded=True),
|
||||
|
|
@ -251,6 +266,7 @@ class LiteLLMAiohttpTransport(AiohttpTransport):
|
|||
),
|
||||
proxy=proxy,
|
||||
server_hostname=sni_hostname,
|
||||
**ssl_kwargs,
|
||||
).__aenter__()
|
||||
|
||||
return response
|
||||
|
|
@ -268,6 +284,9 @@ class LiteLLMAiohttpTransport(AiohttpTransport):
|
|||
# Resolve proxy settings from environment variables
|
||||
proxy = await self._get_proxy_settings(request)
|
||||
|
||||
# Use stored SSL configuration for per-request override
|
||||
ssl_config = self._ssl_verify
|
||||
|
||||
try:
|
||||
with map_aiohttp_exceptions():
|
||||
response = await self._make_aiohttp_request(
|
||||
|
|
@ -276,6 +295,7 @@ class LiteLLMAiohttpTransport(AiohttpTransport):
|
|||
timeout=timeout,
|
||||
proxy=proxy,
|
||||
sni_hostname=sni_hostname,
|
||||
ssl_verify=ssl_config,
|
||||
)
|
||||
except RuntimeError as e:
|
||||
# Handle the case where session was closed between our check and actual use
|
||||
|
|
@ -296,6 +316,7 @@ class LiteLLMAiohttpTransport(AiohttpTransport):
|
|||
timeout=timeout,
|
||||
proxy=proxy,
|
||||
sni_hostname=sni_hostname,
|
||||
ssl_verify=ssl_config,
|
||||
)
|
||||
else:
|
||||
# Re-raise if it's a different RuntimeError
|
||||
|
|
|
|||
|
|
@ -846,6 +846,16 @@ class AsyncHTTPHandler:
|
|||
if str_to_bool(os.getenv("AIOHTTP_TRUST_ENV", "False")) is True:
|
||||
trust_env = True
|
||||
|
||||
#########################################################
|
||||
# Determine SSL config to pass to transport for per-request override
|
||||
# This ensures ssl_verify works even with shared sessions
|
||||
#########################################################
|
||||
ssl_for_transport: Optional[Union[bool, ssl.SSLContext]] = None
|
||||
if ssl_context is not None:
|
||||
ssl_for_transport = ssl_context
|
||||
elif ssl_verify is False:
|
||||
ssl_for_transport = False
|
||||
|
||||
verbose_logger.debug("Creating AiohttpTransport...")
|
||||
|
||||
# Use shared session if provided and valid
|
||||
|
|
@ -853,7 +863,10 @@ class AsyncHTTPHandler:
|
|||
verbose_logger.debug(
|
||||
f"SHARED SESSION: Reusing existing ClientSession (ID: {id(shared_session)})"
|
||||
)
|
||||
return LiteLLMAiohttpTransport(client=shared_session)
|
||||
return LiteLLMAiohttpTransport(
|
||||
client=shared_session,
|
||||
ssl_verify=ssl_for_transport,
|
||||
)
|
||||
|
||||
# Create new session only if none provided or existing one is invalid
|
||||
verbose_logger.debug(
|
||||
|
|
@ -877,6 +890,7 @@ class AsyncHTTPHandler:
|
|||
connector=TCPConnector(**transport_connector_kwargs),
|
||||
trust_env=trust_env,
|
||||
),
|
||||
ssl_verify=ssl_for_transport,
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
|
|
|
|||
|
|
@ -60,6 +60,38 @@ from ...anthropic.chat.transformation import AnthropicConfig
|
|||
from ...openai_like.chat.transformation import OpenAILikeChatConfig
|
||||
from ..common_utils import DatabricksBase, DatabricksException
|
||||
|
||||
def _sanitize_empty_content(message_dict: dict[str, Any]) -> None:
|
||||
"""
|
||||
Remove or filter content so empty text blocks are not sent.
|
||||
Databricks Model Serving uses Anthropic Messages API spec and rejects empty text blocks.
|
||||
"""
|
||||
content = message_dict.get("content")
|
||||
if content is None:
|
||||
message_dict.pop("content", None)
|
||||
return
|
||||
if isinstance(content, str):
|
||||
if not content.strip():
|
||||
message_dict.pop("content")
|
||||
return
|
||||
if isinstance(content, list):
|
||||
if not content:
|
||||
message_dict.pop("content")
|
||||
return
|
||||
filtered = [
|
||||
block
|
||||
for block in content
|
||||
if not (
|
||||
isinstance(block, dict)
|
||||
and block.get("type") == "text"
|
||||
and not (block.get("text") or "").strip()
|
||||
)
|
||||
]
|
||||
if not filtered:
|
||||
message_dict.pop("content")
|
||||
else:
|
||||
message_dict["content"] = filtered
|
||||
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as _LiteLLMLoggingObj
|
||||
|
||||
|
|
@ -350,6 +382,7 @@ class DatabricksConfig(DatabricksBase, OpenAILikeChatConfig, AnthropicConfig):
|
|||
# Move message-level cache_control into a content block when content is a string.
|
||||
if "cache_control" in _message and isinstance(_message.get("content"), str):
|
||||
_message = self._move_cache_control_into_string_content_block(_message)
|
||||
_sanitize_empty_content(cast(dict[str, Any], _message))
|
||||
new_messages.append(_message)
|
||||
|
||||
if is_async:
|
||||
|
|
|
|||
|
|
@ -502,13 +502,12 @@ class OllamaChatCompletionResponseIterator(BaseModelResponseIterator):
|
|||
reasoning_content: Optional[str] = None
|
||||
content: Optional[str] = None
|
||||
if chunk["message"].get("thinking") is not None:
|
||||
if self.started_reasoning_content is False:
|
||||
reasoning_content = chunk["message"].get("thinking")
|
||||
self.started_reasoning_content = True
|
||||
elif self.finished_reasoning_content is False:
|
||||
reasoning_content = chunk["message"].get("thinking")
|
||||
self.finished_reasoning_content = True
|
||||
reasoning_content = chunk["message"].get("thinking")
|
||||
self.started_reasoning_content = True
|
||||
elif chunk["message"].get("content") is not None:
|
||||
if self.started_reasoning_content and not self.finished_reasoning_content:
|
||||
self.finished_reasoning_content = True
|
||||
|
||||
message_content = chunk["message"].get("content")
|
||||
if "<think>" in message_content:
|
||||
message_content = message_content.replace("<think>", "")
|
||||
|
|
|
|||
7
litellm/llms/perplexity/responses/__init__.py
Normal file
7
litellm/llms/perplexity/responses/__init__.py
Normal file
|
|
@ -0,0 +1,7 @@
|
|||
"""
|
||||
Perplexity Agentic Research API (Responses API) module
|
||||
"""
|
||||
|
||||
from .transformation import PerplexityResponsesConfig
|
||||
|
||||
__all__ = ["PerplexityResponsesConfig"]
|
||||
409
litellm/llms/perplexity/responses/transformation.py
Normal file
409
litellm/llms/perplexity/responses/transformation.py
Normal file
|
|
@ -0,0 +1,409 @@
|
|||
"""
|
||||
Transformation logic for Perplexity Agentic Research API (Responses API)
|
||||
|
||||
This module handles the translation between OpenAI's Responses API format
|
||||
and Perplexity's Responses API format, which supports:
|
||||
- Third-party model access (OpenAI, Anthropic, Google, xAI, etc.)
|
||||
- Presets for optimized configurations
|
||||
- Web search and URL fetching tools
|
||||
- Reasoning effort control
|
||||
- Instructions parameter for system-level guidance
|
||||
"""
|
||||
|
||||
from typing import Any, Dict, List, Optional, Union
|
||||
|
||||
import httpx
|
||||
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj
|
||||
from litellm.llms.base_llm.chat.transformation import BaseLLMException
|
||||
from litellm.llms.openai.responses.transformation import OpenAIResponsesAPIConfig
|
||||
from litellm.secret_managers.main import get_secret_str
|
||||
from litellm.types.llms.openai import (
|
||||
ResponseAPIUsage,
|
||||
ResponseInputParam,
|
||||
ResponsesAPIOptionalRequestParams,
|
||||
ResponsesAPIResponse,
|
||||
ResponsesAPIStreamingResponse,
|
||||
)
|
||||
from litellm.types.router import GenericLiteLLMParams
|
||||
from litellm.types.utils import LlmProviders
|
||||
|
||||
|
||||
class PerplexityResponsesConfig(OpenAIResponsesAPIConfig):
|
||||
"""
|
||||
Configuration for Perplexity Agentic Research API (Responses API)
|
||||
|
||||
|
||||
Reference: https://docs.perplexity.ai/agentic-research/quickstart
|
||||
"""
|
||||
|
||||
@property
|
||||
def custom_llm_provider(self) -> LlmProviders:
|
||||
return LlmProviders.PERPLEXITY
|
||||
|
||||
def get_supported_openai_params(self, model: str) -> list:
|
||||
"""
|
||||
Perplexity Responses API supports a different set of parameters
|
||||
|
||||
Ref: https://docs.perplexity.ai/api-reference/responses-post
|
||||
"""
|
||||
return [
|
||||
"max_output_tokens",
|
||||
"stream",
|
||||
"temperature",
|
||||
"top_p",
|
||||
"tools",
|
||||
"reasoning",
|
||||
"preset",
|
||||
"instructions",
|
||||
"models", # Model fallback support
|
||||
]
|
||||
|
||||
def validate_environment(
|
||||
self, headers: dict, model: str, litellm_params: Optional[GenericLiteLLMParams]
|
||||
) -> dict:
|
||||
"""Validate environment and set up headers"""
|
||||
# Get API key from environment
|
||||
api_key = (
|
||||
get_secret_str("PERPLEXITYAI_API_KEY")
|
||||
or get_secret_str("PERPLEXITY_API_KEY")
|
||||
)
|
||||
|
||||
if api_key:
|
||||
headers["Authorization"] = f"Bearer {api_key}"
|
||||
|
||||
headers["Content-Type"] = "application/json"
|
||||
|
||||
return headers
|
||||
|
||||
def get_complete_url(
|
||||
self,
|
||||
api_base: Optional[str],
|
||||
litellm_params: dict,
|
||||
) -> str:
|
||||
"""Get the complete URL for the Perplexity Responses API"""
|
||||
if api_base is None:
|
||||
api_base = get_secret_str("PERPLEXITY_API_BASE") or "https://api.perplexity.ai"
|
||||
|
||||
# Ensure api_base doesn't end with a slash
|
||||
api_base = api_base.rstrip("/")
|
||||
|
||||
# Add the responses endpoint
|
||||
return f"{api_base}/v1/responses"
|
||||
|
||||
def map_openai_params(
|
||||
self,
|
||||
response_api_optional_params: ResponsesAPIOptionalRequestParams,
|
||||
model: str,
|
||||
drop_params: bool,
|
||||
) -> Dict:
|
||||
"""
|
||||
Map OpenAI Responses API parameters to Perplexity format
|
||||
|
||||
Key differences:
|
||||
- Supports 'preset' parameter for predefined configurations
|
||||
- Supports 'instructions' parameter for system-level guidance
|
||||
- Tools are specified differently (web_search, fetch_url)
|
||||
"""
|
||||
mapped_params: Dict[str, Any] = {}
|
||||
|
||||
# Map standard parameters
|
||||
if response_api_optional_params.get("max_output_tokens"):
|
||||
mapped_params["max_output_tokens"] = response_api_optional_params["max_output_tokens"]
|
||||
|
||||
if response_api_optional_params.get("temperature"):
|
||||
mapped_params["temperature"] = response_api_optional_params["temperature"]
|
||||
|
||||
if response_api_optional_params.get("top_p"):
|
||||
mapped_params["top_p"] = response_api_optional_params["top_p"]
|
||||
|
||||
if response_api_optional_params.get("stream"):
|
||||
mapped_params["stream"] = response_api_optional_params["stream"]
|
||||
|
||||
if response_api_optional_params.get("stream_options"):
|
||||
mapped_params["stream_options"] = response_api_optional_params["stream_options"]
|
||||
|
||||
# Map Perplexity-specific parameters (using .get() with Any dict access)
|
||||
preset = response_api_optional_params.get("preset") # type: ignore
|
||||
if preset:
|
||||
mapped_params["preset"] = preset
|
||||
|
||||
instructions = response_api_optional_params.get("instructions") # type: ignore
|
||||
if instructions:
|
||||
mapped_params["instructions"] = instructions
|
||||
|
||||
if response_api_optional_params.get("reasoning"):
|
||||
mapped_params["reasoning"] = response_api_optional_params["reasoning"]
|
||||
|
||||
tools = response_api_optional_params.get("tools")
|
||||
if tools:
|
||||
# Convert tools to list of dicts for transformation
|
||||
tools_list = [dict(tool) if hasattr(tool, '__dict__') else tool for tool in tools] # type: ignore
|
||||
mapped_params["tools"] = self._transform_tools(tools_list) # type: ignore
|
||||
|
||||
return mapped_params
|
||||
|
||||
def _transform_tools(self, tools: List[Dict[str, Any]]) -> List[Dict[str, Any]]:
|
||||
"""
|
||||
Transform tools to Perplexity format
|
||||
|
||||
Perplexity supports:
|
||||
- web_search: Performs web searches
|
||||
- fetch_url: Fetches content from URLs
|
||||
"""
|
||||
perplexity_tools = []
|
||||
|
||||
for tool in tools:
|
||||
if isinstance(tool, dict):
|
||||
tool_type = tool.get("type")
|
||||
|
||||
# Direct Perplexity tool format
|
||||
if tool_type in ["web_search", "fetch_url"]:
|
||||
perplexity_tools.append(tool)
|
||||
|
||||
# OpenAI function format - try to map to Perplexity tools
|
||||
elif tool_type == "function":
|
||||
function = tool.get("function", {})
|
||||
function_name = function.get("name", "")
|
||||
|
||||
if function_name == "web_search" or "search" in function_name.lower():
|
||||
perplexity_tools.append({"type": "web_search"})
|
||||
elif function_name == "fetch_url" or "fetch" in function_name.lower():
|
||||
perplexity_tools.append({"type": "fetch_url"})
|
||||
|
||||
return perplexity_tools
|
||||
|
||||
def transform_responses_api_request(
|
||||
self,
|
||||
model: str,
|
||||
input: Union[str, ResponseInputParam],
|
||||
response_api_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
headers: dict,
|
||||
) -> Dict:
|
||||
"""
|
||||
Transform request to Perplexity Responses API format
|
||||
"""
|
||||
# Check if the model is a preset (format: preset/preset-name)
|
||||
if model.startswith("preset/"):
|
||||
preset_name = model.replace("preset/", "")
|
||||
data = {
|
||||
"preset": preset_name,
|
||||
"input": self._format_input(input),
|
||||
}
|
||||
# Check if preset is explicitly provided in params
|
||||
elif response_api_optional_request_params.get("preset"):
|
||||
data = {
|
||||
"preset": response_api_optional_request_params.pop("preset"),
|
||||
"input": self._format_input(input),
|
||||
}
|
||||
else:
|
||||
# Full request format for third-party models
|
||||
data = {
|
||||
"model": model,
|
||||
"input": self._format_input(input),
|
||||
}
|
||||
|
||||
# Add all optional parameters
|
||||
for key, value in response_api_optional_request_params.items():
|
||||
data[key] = value
|
||||
|
||||
return data
|
||||
|
||||
def _format_input(self, input: Union[str, ResponseInputParam]) -> Union[str, List[Dict[str, Any]]]:
|
||||
"""
|
||||
Format input for Perplexity Responses API
|
||||
|
||||
The API accepts either:
|
||||
- A simple string for single-turn queries
|
||||
- An array of message objects for multi-turn conversations
|
||||
"""
|
||||
if isinstance(input, str):
|
||||
return input
|
||||
|
||||
# Handle ResponseInputParam format
|
||||
if isinstance(input, list):
|
||||
formatted_messages = []
|
||||
for item in input:
|
||||
if isinstance(item, dict):
|
||||
formatted_message = {
|
||||
"type": "message",
|
||||
"role": item.get("role"),
|
||||
"content": item.get("content", ""),
|
||||
}
|
||||
formatted_messages.append(formatted_message)
|
||||
return formatted_messages
|
||||
|
||||
return str(input)
|
||||
|
||||
def transform_response_api_response(
|
||||
self,
|
||||
model: str,
|
||||
raw_response: httpx.Response,
|
||||
logging_obj: LiteLLMLoggingObj,
|
||||
) -> ResponsesAPIResponse:
|
||||
"""
|
||||
Transform Perplexity Responses API response to OpenAI Responses API format
|
||||
"""
|
||||
try:
|
||||
raw_response_json = raw_response.json()
|
||||
except Exception as e:
|
||||
raise BaseLLMException(
|
||||
status_code=raw_response.status_code,
|
||||
message=f"Failed to parse response: {str(e)}",
|
||||
)
|
||||
|
||||
# Check for error status
|
||||
status = raw_response_json.get("status")
|
||||
if status == "failed":
|
||||
error = raw_response_json.get("error", {})
|
||||
error_message = error.get("message", "Unknown error")
|
||||
raise BaseLLMException(
|
||||
status_code=raw_response.status_code,
|
||||
message=error_message,
|
||||
)
|
||||
|
||||
# Transform usage to handle Perplexity's cost structure
|
||||
usage_data = raw_response_json.get("usage", {})
|
||||
transformed_usage_dict = self._transform_usage(usage_data)
|
||||
|
||||
# Convert usage dict to ResponseAPIUsage object
|
||||
usage_obj = ResponseAPIUsage(**transformed_usage_dict) if transformed_usage_dict else None
|
||||
|
||||
# Map Perplexity response to OpenAI Responses API format
|
||||
response = ResponsesAPIResponse(
|
||||
id=raw_response_json.get("id", ""),
|
||||
object="response",
|
||||
created_at=raw_response_json.get("created_at", 0),
|
||||
status=raw_response_json.get("status", "completed"),
|
||||
model=raw_response_json.get("model", model),
|
||||
output=raw_response_json.get("output", []),
|
||||
usage=usage_obj,
|
||||
)
|
||||
|
||||
return response
|
||||
|
||||
def _transform_usage(self, usage_data: Dict[str, Any]) -> Dict[str, Any]:
|
||||
"""
|
||||
Transform Perplexity usage data to OpenAI format
|
||||
|
||||
Perplexity returns:
|
||||
{
|
||||
"input_tokens": 100,
|
||||
"output_tokens": 200,
|
||||
"total_tokens": 300,
|
||||
"cost": {
|
||||
"currency": "USD",
|
||||
"input_cost": 0.0001,
|
||||
"output_cost": 0.0002,
|
||||
"total_cost": 0.0003
|
||||
}
|
||||
}
|
||||
|
||||
OpenAI expects:
|
||||
{
|
||||
"input_tokens": 100,
|
||||
"output_tokens": 200,
|
||||
"total_tokens": 300,
|
||||
"cost": 0.0003
|
||||
}
|
||||
"""
|
||||
transformed = {
|
||||
"input_tokens": usage_data.get("input_tokens", 0),
|
||||
"output_tokens": usage_data.get("output_tokens", 0),
|
||||
"total_tokens": usage_data.get("total_tokens", 0),
|
||||
}
|
||||
|
||||
# Transform cost from Perplexity format (dict) to OpenAI format (float)
|
||||
cost_obj = usage_data.get("cost")
|
||||
if isinstance(cost_obj, dict) and "total_cost" in cost_obj:
|
||||
transformed["cost"] = cost_obj["total_cost"]
|
||||
verbose_logger.debug(
|
||||
"Transformed Perplexity cost object to float: %s -> %s",
|
||||
cost_obj,
|
||||
cost_obj["total_cost"]
|
||||
)
|
||||
elif cost_obj is not None:
|
||||
# If cost is already a float/number, use it as-is
|
||||
transformed["cost"] = cost_obj
|
||||
|
||||
# Add input_tokens_details if present
|
||||
if "input_tokens_details" in usage_data:
|
||||
transformed["input_tokens_details"] = usage_data["input_tokens_details"]
|
||||
|
||||
# Add output_tokens_details if present
|
||||
if "output_tokens_details" in usage_data:
|
||||
transformed["output_tokens_details"] = usage_data["output_tokens_details"]
|
||||
|
||||
return transformed
|
||||
|
||||
def transform_streaming_response(
|
||||
self,
|
||||
model: str,
|
||||
parsed_chunk: dict,
|
||||
logging_obj: LiteLLMLoggingObj,
|
||||
) -> ResponsesAPIStreamingResponse:
|
||||
"""
|
||||
Transform a parsed streaming response chunk into a ResponsesAPIStreamingResponse
|
||||
"""
|
||||
# Get the event type from the chunk
|
||||
verbose_logger.debug("Raw Perplexity Chunk=%s", parsed_chunk)
|
||||
event_type = str(parsed_chunk.get("type"))
|
||||
event_pydantic_model = PerplexityResponsesConfig.get_event_model_class(
|
||||
event_type=event_type
|
||||
)
|
||||
|
||||
# Transform Perplexity-specific fields to OpenAI format
|
||||
parsed_chunk = self._transform_perplexity_chunk(parsed_chunk)
|
||||
|
||||
# Defensive: Handle error.code being null (similar to OpenAI implementation)
|
||||
try:
|
||||
error_obj = parsed_chunk.get("error")
|
||||
if isinstance(error_obj, dict) and error_obj.get("code") is None:
|
||||
# Preserve other fields, but ensure `code` is a non-null string
|
||||
parsed_chunk = dict(parsed_chunk)
|
||||
parsed_chunk["error"] = dict(error_obj)
|
||||
parsed_chunk["error"]["code"] = "unknown_error"
|
||||
except Exception:
|
||||
# If anything unexpected happens here, fall back to attempting
|
||||
# instantiation and let higher-level handlers manage errors.
|
||||
verbose_logger.debug("Failed to coalesce error.code in parsed_chunk")
|
||||
|
||||
return event_pydantic_model(**parsed_chunk)
|
||||
|
||||
def _transform_perplexity_chunk(self, chunk: dict) -> dict:
|
||||
"""
|
||||
Transform Perplexity-specific fields in a streaming chunk to OpenAI format.
|
||||
|
||||
This handles:
|
||||
- Converting Perplexity's cost object to a simple float
|
||||
"""
|
||||
# Make a copy to avoid modifying the original
|
||||
chunk = dict(chunk)
|
||||
|
||||
# Transform usage.cost from Perplexity format to OpenAI format
|
||||
# Perplexity: {"currency": "USD", "input_cost": 0.0001, "output_cost": 0.0002, "total_cost": 0.0003}
|
||||
# OpenAI: 0.0003 (just the total_cost as a float)
|
||||
try:
|
||||
response_obj = chunk.get("response")
|
||||
if isinstance(response_obj, dict):
|
||||
usage_obj = response_obj.get("usage")
|
||||
if isinstance(usage_obj, dict):
|
||||
cost_obj = usage_obj.get("cost")
|
||||
if isinstance(cost_obj, dict) and "total_cost" in cost_obj:
|
||||
# Replace the cost object with just the total_cost value
|
||||
chunk = dict(chunk)
|
||||
chunk["response"] = dict(response_obj)
|
||||
chunk["response"]["usage"] = dict(usage_obj)
|
||||
chunk["response"]["usage"]["cost"] = cost_obj["total_cost"]
|
||||
verbose_logger.debug(
|
||||
"Transformed Perplexity cost object to float: %s -> %s",
|
||||
cost_obj,
|
||||
cost_obj["total_cost"]
|
||||
)
|
||||
except Exception as e:
|
||||
# If transformation fails, log and continue with original chunk
|
||||
verbose_logger.debug("Failed to transform Perplexity cost object: %s", e)
|
||||
|
||||
return chunk
|
||||
|
|
@ -1,4 +1,5 @@
|
|||
import re
|
||||
from copy import deepcopy
|
||||
from enum import Enum
|
||||
from typing import Any, Dict, List, Literal, Optional, Set, Tuple, Union, get_type_hints
|
||||
|
||||
|
|
@ -684,7 +685,7 @@ def convert_anyof_null_to_nullable(schema, depth=0):
|
|||
if anyof is not None:
|
||||
contains_null = False
|
||||
for atype in anyof:
|
||||
if atype == {"type": "null"}:
|
||||
if isinstance(atype, dict) and atype.get("type") == "null":
|
||||
# remove null type
|
||||
anyof.remove(atype)
|
||||
contains_null = True
|
||||
|
|
@ -801,8 +802,38 @@ def _convert_schema_types(schema, depth=0):
|
|||
if "type" in schema:
|
||||
type_val = schema["type"]
|
||||
if isinstance(type_val, list) and len(type_val) > 1:
|
||||
# Convert ["string", "number"] -> {"anyOf": [{"type": "STRING"}, {"type": "NUMBER"}]}
|
||||
schema["anyOf"] = [{"type": t} for t in type_val if isinstance(t, str)]
|
||||
# Convert type arrays to anyOf format
|
||||
# Fields that are specific to object/array types and should move into anyOf
|
||||
type_specific_fields = {"properties", "required", "additionalProperties", "items", "minItems", "maxItems", "minProperties", "maxProperties"}
|
||||
|
||||
any_of: List[Dict[str, Any]] = []
|
||||
for t in type_val:
|
||||
if not isinstance(t, str):
|
||||
continue
|
||||
if t == "null":
|
||||
# Keep null entry minimal so we can strip it later.
|
||||
any_of.append({"type": "null"})
|
||||
continue
|
||||
|
||||
# For object/array types, include type-specific fields
|
||||
if t in ("object", "array"):
|
||||
item_schema = {"type": t}
|
||||
# Move type-specific fields into this anyOf item
|
||||
for field in type_specific_fields:
|
||||
if field in schema:
|
||||
item_schema[field] = deepcopy(schema[field])
|
||||
any_of.append(item_schema)
|
||||
else:
|
||||
# For primitive types, only include the type
|
||||
any_of.append({"type": t})
|
||||
|
||||
# Remove type-specific fields from parent if we moved them into anyOf
|
||||
has_object_or_array = any(t in ("object", "array") for t in type_val if isinstance(t, str))
|
||||
if has_object_or_array:
|
||||
for field in type_specific_fields:
|
||||
schema.pop(field, None)
|
||||
|
||||
schema["anyOf"] = any_of
|
||||
schema.pop("type")
|
||||
elif isinstance(type_val, list) and len(type_val) == 1:
|
||||
schema["type"] = type_val[0]
|
||||
|
|
|
|||
|
|
@ -437,6 +437,27 @@ def _gemini_convert_messages_with_history( # noqa: PLR0915
|
|||
else:
|
||||
assistant_content.append(PartType(text=assistant_text)) # type: ignore
|
||||
|
||||
## HANDLE ASSISTANT IMAGES FIELD
|
||||
# Process images field if present (for generated images from assistant)
|
||||
assistant_images = assistant_msg.get("images")
|
||||
if assistant_images is not None and isinstance(assistant_images, list):
|
||||
for image_item in assistant_images:
|
||||
if isinstance(image_item, dict):
|
||||
image_url_obj = image_item.get("image_url")
|
||||
if isinstance(image_url_obj, dict):
|
||||
assistant_image_url = image_url_obj.get("url")
|
||||
format = image_url_obj.get("format")
|
||||
detail = image_url_obj.get("detail")
|
||||
media_resolution_enum = _convert_detail_to_media_resolution_enum(detail)
|
||||
if assistant_image_url:
|
||||
_part = _process_gemini_media(
|
||||
image_url=assistant_image_url,
|
||||
format=format,
|
||||
media_resolution_enum=media_resolution_enum,
|
||||
model=model,
|
||||
)
|
||||
assistant_content.append(_part)
|
||||
|
||||
## HANDLE ASSISTANT FUNCTION CALL
|
||||
if (
|
||||
assistant_msg.get("tool_calls", []) is not None
|
||||
|
|
|
|||
|
|
@ -107,6 +107,11 @@ class VertexAIPartnerModelsTokenCounter(VertexBase):
|
|||
vertex_project = self.get_vertex_ai_project(litellm_params)
|
||||
vertex_location = self.get_vertex_ai_location(litellm_params)
|
||||
|
||||
# Map empty location/cluade models to a supported region for count-tokens endpoint
|
||||
# https://docs.cloud.google.com/vertex-ai/generative-ai/docs/partner-models/claude/count-tokens
|
||||
if not vertex_location or "claude" in model.lower():
|
||||
vertex_location = "us-central1"
|
||||
|
||||
# Get access token and resolved project ID
|
||||
access_token, project_id = await self._ensure_access_token_async(
|
||||
credentials=vertex_credentials,
|
||||
|
|
@ -118,7 +123,7 @@ class VertexAIPartnerModelsTokenCounter(VertexBase):
|
|||
endpoint_url = self._build_count_tokens_endpoint(
|
||||
model=model,
|
||||
project_id=project_id,
|
||||
vertex_location=vertex_location or "us-central1",
|
||||
vertex_location=vertex_location,
|
||||
api_base=litellm_params.get("api_base"),
|
||||
)
|
||||
|
||||
|
|
|
|||
|
|
@ -5848,6 +5848,19 @@
|
|||
"output_cost_per_token": 7e-07,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
"azure_ai/kimi-k2.5": {
|
||||
"input_cost_per_token": 6e-07,
|
||||
"litellm_provider": "azure_ai",
|
||||
"max_input_tokens": 262144,
|
||||
"max_output_tokens": 262144,
|
||||
"max_tokens": 262144,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 3e-06,
|
||||
"source": "https://techcommunity.microsoft.com/blog/azure-ai-foundry-blog/kimi-k2-5-now-in-microsoft-foundry/4492321",
|
||||
"supports_function_calling": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_vision": true
|
||||
},
|
||||
"azure_ai/ministral-3b": {
|
||||
"input_cost_per_token": 4e-08,
|
||||
"litellm_provider": "azure_ai",
|
||||
|
|
@ -6091,6 +6104,28 @@
|
|||
"output_cost_per_token": 2.4e-05,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
"bedrock/ap-northeast-1/moonshotai.kimi-k2-thinking": {
|
||||
"input_cost_per_token": 7.3e-07,
|
||||
"litellm_provider": "bedrock",
|
||||
"max_input_tokens": 262144,
|
||||
"max_output_tokens": 262144,
|
||||
"max_tokens": 262144,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 3.03e-06,
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true
|
||||
},
|
||||
"bedrock/moonshotai.kimi-k2.5": {
|
||||
"input_cost_per_token": 7.3e-07,
|
||||
"litellm_provider": "bedrock",
|
||||
"max_input_tokens": 262144,
|
||||
"max_output_tokens": 262144,
|
||||
"max_tokens": 262144,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 3.03e-06,
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true
|
||||
},
|
||||
"bedrock/ap-south-1/meta.llama3-70b-instruct-v1:0": {
|
||||
"input_cost_per_token": 3.18e-06,
|
||||
"litellm_provider": "bedrock",
|
||||
|
|
@ -6109,6 +6144,17 @@
|
|||
"mode": "chat",
|
||||
"output_cost_per_token": 7.2e-07
|
||||
},
|
||||
"bedrock/ap-south-1/moonshotai.kimi-k2-thinking": {
|
||||
"input_cost_per_token": 7.1e-07,
|
||||
"litellm_provider": "bedrock",
|
||||
"max_input_tokens": 262144,
|
||||
"max_output_tokens": 262144,
|
||||
"max_tokens": 262144,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 2.94e-06,
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true
|
||||
},
|
||||
"bedrock/ca-central-1/meta.llama3-70b-instruct-v1:0": {
|
||||
"input_cost_per_token": 3.05e-06,
|
||||
"litellm_provider": "bedrock",
|
||||
|
|
@ -6314,6 +6360,17 @@
|
|||
"mode": "chat",
|
||||
"output_cost_per_token": 1.01e-06
|
||||
},
|
||||
"bedrock/sa-east-1/moonshotai.kimi-k2-thinking": {
|
||||
"input_cost_per_token": 7.3e-07,
|
||||
"litellm_provider": "bedrock",
|
||||
"max_input_tokens": 262144,
|
||||
"max_output_tokens": 262144,
|
||||
"max_tokens": 262144,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 3.03e-06,
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true
|
||||
},
|
||||
"bedrock/us-east-1/1-month-commitment/anthropic.claude-instant-v1": {
|
||||
"input_cost_per_second": 0.011,
|
||||
"litellm_provider": "bedrock",
|
||||
|
|
@ -6450,6 +6507,28 @@
|
|||
"output_cost_per_token": 7e-07,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
"bedrock/us-east-1/moonshotai.kimi-k2-thinking": {
|
||||
"input_cost_per_token": 6e-07,
|
||||
"litellm_provider": "bedrock",
|
||||
"max_input_tokens": 262144,
|
||||
"max_output_tokens": 262144,
|
||||
"max_tokens": 262144,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 2.5e-06,
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true
|
||||
},
|
||||
"bedrock/us-east-2/moonshotai.kimi-k2-thinking": {
|
||||
"input_cost_per_token": 6e-07,
|
||||
"litellm_provider": "bedrock",
|
||||
"max_input_tokens": 262144,
|
||||
"max_output_tokens": 262144,
|
||||
"max_tokens": 262144,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 2.5e-06,
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true
|
||||
},
|
||||
"bedrock/us-gov-east-1/amazon.nova-pro-v1:0": {
|
||||
"input_cost_per_token": 9.6e-07,
|
||||
"litellm_provider": "bedrock",
|
||||
|
|
@ -6856,6 +6935,17 @@
|
|||
"output_cost_per_token": 7e-07,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
"bedrock/us-west-2/moonshotai.kimi-k2-thinking": {
|
||||
"input_cost_per_token": 6e-07,
|
||||
"litellm_provider": "bedrock",
|
||||
"max_input_tokens": 262144,
|
||||
"max_output_tokens": 262144,
|
||||
"max_tokens": 262144,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 2.5e-06,
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true
|
||||
},
|
||||
"bedrock/us.anthropic.claude-3-5-haiku-20241022-v1:0": {
|
||||
"cache_creation_input_token_cost": 1e-06,
|
||||
"cache_read_input_token_cost": 8e-08,
|
||||
|
|
@ -25614,6 +25704,66 @@
|
|||
"supports_function_calling": true,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
"perplexity/preset/pro-search": {
|
||||
"litellm_provider": "perplexity",
|
||||
"mode": "responses",
|
||||
"supports_web_search": true,
|
||||
"supports_preset": true
|
||||
},
|
||||
"perplexity/openai/gpt-4o": {
|
||||
"litellm_provider": "perplexity",
|
||||
"mode": "responses",
|
||||
"supports_web_search": true,
|
||||
"supports_reasoning": false
|
||||
},
|
||||
"perplexity/openai/gpt-4o-mini": {
|
||||
"litellm_provider": "perplexity",
|
||||
"mode": "responses",
|
||||
"supports_web_search": true,
|
||||
"supports_reasoning": false
|
||||
},
|
||||
"perplexity/openai/gpt-5.2": {
|
||||
"litellm_provider": "perplexity",
|
||||
"mode": "responses",
|
||||
"supports_web_search": true,
|
||||
"supports_reasoning": true
|
||||
},
|
||||
"perplexity/anthropic/claude-3-5-sonnet-20241022": {
|
||||
"litellm_provider": "perplexity",
|
||||
"mode": "responses",
|
||||
"supports_web_search": true,
|
||||
"supports_reasoning": false
|
||||
},
|
||||
"perplexity/anthropic/claude-3-5-haiku-20241022": {
|
||||
"litellm_provider": "perplexity",
|
||||
"mode": "responses",
|
||||
"supports_web_search": true,
|
||||
"supports_reasoning": false
|
||||
},
|
||||
"perplexity/google/gemini-2.0-flash-exp": {
|
||||
"litellm_provider": "perplexity",
|
||||
"mode": "responses",
|
||||
"supports_web_search": true,
|
||||
"supports_reasoning": false
|
||||
},
|
||||
"perplexity/google/gemini-2.0-flash-thinking-exp": {
|
||||
"litellm_provider": "perplexity",
|
||||
"mode": "responses",
|
||||
"supports_web_search": true,
|
||||
"supports_reasoning": true
|
||||
},
|
||||
"perplexity/xai/grok-2-1212": {
|
||||
"litellm_provider": "perplexity",
|
||||
"mode": "responses",
|
||||
"supports_web_search": true,
|
||||
"supports_reasoning": false
|
||||
},
|
||||
"perplexity/xai/grok-2-vision-1212": {
|
||||
"litellm_provider": "perplexity",
|
||||
"mode": "responses",
|
||||
"supports_web_search": true,
|
||||
"supports_reasoning": false
|
||||
},
|
||||
"publicai/aisingapore/Qwen-SEA-LION-v4-32B-IT": {
|
||||
"input_cost_per_token": 0.0,
|
||||
"litellm_provider": "publicai",
|
||||
|
|
|
|||
|
|
@ -16,6 +16,7 @@ from litellm.proxy.common_utils.encrypt_decrypt_utils import (
|
|||
)
|
||||
from litellm.proxy.common_utils.http_parsing_utils import _read_request_body
|
||||
from litellm.proxy.utils import get_server_root_path
|
||||
from litellm.types.mcp import MCPAuth
|
||||
from litellm.types.mcp_server.mcp_server_manager import MCPServer
|
||||
|
||||
router = APIRouter(
|
||||
|
|
@ -125,6 +126,29 @@ def decode_state_hash(encrypted_state: str) -> dict:
|
|||
return state_data
|
||||
|
||||
|
||||
def _resolve_oauth2_server_for_root_endpoints(
|
||||
client_ip: Optional[str] = None,
|
||||
) -> Optional[MCPServer]:
|
||||
"""
|
||||
Resolve the MCP server for root-level OAuth endpoints (no server name in path).
|
||||
|
||||
When the MCP SDK hits root-level endpoints like /register, /authorize, /token
|
||||
without a server name prefix, we try to find the right server automatically.
|
||||
Returns the server if exactly one OAuth2 server is configured, else None.
|
||||
"""
|
||||
from litellm.proxy._experimental.mcp_server.mcp_server_manager import (
|
||||
global_mcp_server_manager,
|
||||
)
|
||||
|
||||
registry = global_mcp_server_manager.get_filtered_registry(client_ip=client_ip)
|
||||
oauth2_servers = [
|
||||
s for s in registry.values() if s.auth_type == MCPAuth.oauth2
|
||||
]
|
||||
if len(oauth2_servers) == 1:
|
||||
return oauth2_servers[0]
|
||||
return None
|
||||
|
||||
|
||||
async def authorize_with_server(
|
||||
request: Request,
|
||||
mcp_server: MCPServer,
|
||||
|
|
@ -305,6 +329,8 @@ async def authorize(
|
|||
mcp_server = global_mcp_server_manager.get_mcp_server_by_name(
|
||||
lookup_name, client_ip=client_ip
|
||||
)
|
||||
if mcp_server is None and mcp_server_name is None:
|
||||
mcp_server = _resolve_oauth2_server_for_root_endpoints()
|
||||
if mcp_server is None:
|
||||
raise HTTPException(status_code=404, detail="MCP server not found")
|
||||
return await authorize_with_server(
|
||||
|
|
@ -350,6 +376,8 @@ async def token_endpoint(
|
|||
mcp_server = global_mcp_server_manager.get_mcp_server_by_name(
|
||||
lookup_name, client_ip=client_ip
|
||||
)
|
||||
if mcp_server is None and mcp_server_name is None:
|
||||
mcp_server = _resolve_oauth2_server_for_root_endpoints()
|
||||
if mcp_server is None:
|
||||
raise HTTPException(status_code=404, detail="MCP server not found")
|
||||
return await exchange_token_with_server(
|
||||
|
|
@ -430,6 +458,13 @@ def _build_oauth_protected_resource_response(
|
|||
)
|
||||
|
||||
request_base_url = get_request_base_url(request)
|
||||
|
||||
# When no server name provided, try to resolve the single OAuth2 server
|
||||
if mcp_server_name is None:
|
||||
resolved = _resolve_oauth2_server_for_root_endpoints()
|
||||
if resolved:
|
||||
mcp_server_name = resolved.server_name or resolved.name
|
||||
|
||||
mcp_server: Optional[MCPServer] = None
|
||||
if mcp_server_name:
|
||||
client_ip = IPAddressUtils.get_mcp_client_ip(request)
|
||||
|
|
@ -535,6 +570,12 @@ def _build_oauth_authorization_server_response(
|
|||
|
||||
request_base_url = get_request_base_url(request)
|
||||
|
||||
# When no server name provided, try to resolve the single OAuth2 server
|
||||
if mcp_server_name is None:
|
||||
resolved = _resolve_oauth2_server_for_root_endpoints()
|
||||
if resolved:
|
||||
mcp_server_name = resolved.server_name or resolved.name
|
||||
|
||||
authorization_endpoint = (
|
||||
f"{request_base_url}/{mcp_server_name}/authorize"
|
||||
if mcp_server_name
|
||||
|
|
@ -640,6 +681,19 @@ async def register_client(request: Request, mcp_server_name: Optional[str] = Non
|
|||
"redirect_uris": [f"{request_base_url}/callback"],
|
||||
}
|
||||
if not mcp_server_name:
|
||||
resolved = _resolve_oauth2_server_for_root_endpoints()
|
||||
if resolved:
|
||||
return await register_client_with_server(
|
||||
request=request,
|
||||
mcp_server=resolved,
|
||||
client_name=data.get("client_name", ""),
|
||||
grant_types=data.get("grant_types", []),
|
||||
response_types=data.get("response_types", []),
|
||||
token_endpoint_auth_method=data.get(
|
||||
"token_endpoint_auth_method", ""
|
||||
),
|
||||
fallback_client_id=resolved.server_name or resolved.name,
|
||||
)
|
||||
return dummy_return
|
||||
|
||||
client_ip = IPAddressUtils.get_mcp_client_ip(request)
|
||||
|
|
|
|||
|
|
@ -341,7 +341,7 @@ class MCPServerManager:
|
|||
verbose_logger.info(
|
||||
f"Loading OpenAPI spec from {spec_path} for server {server_name}"
|
||||
)
|
||||
self._register_openapi_tools(
|
||||
await self._register_openapi_tools(
|
||||
spec_path=spec_path,
|
||||
server=new_server,
|
||||
base_url=server_config.get("url", ""),
|
||||
|
|
@ -353,7 +353,9 @@ class MCPServerManager:
|
|||
|
||||
self.initialize_tool_name_to_mcp_server_name_mapping()
|
||||
|
||||
def _register_openapi_tools(self, spec_path: str, server: MCPServer, base_url: str):
|
||||
async def _register_openapi_tools(
|
||||
self, spec_path: str, server: MCPServer, base_url: str
|
||||
):
|
||||
"""
|
||||
Register tools from an OpenAPI specification for a given server.
|
||||
|
||||
|
|
@ -375,15 +377,15 @@ class MCPServerManager:
|
|||
get_base_url as get_openapi_base_url,
|
||||
)
|
||||
from litellm.proxy._experimental.mcp_server.openapi_to_mcp_generator import (
|
||||
load_openapi_spec,
|
||||
load_openapi_spec_async,
|
||||
)
|
||||
from litellm.proxy._experimental.mcp_server.tool_registry import (
|
||||
global_mcp_tool_registry,
|
||||
)
|
||||
|
||||
try:
|
||||
# Load OpenAPI spec
|
||||
spec = load_openapi_spec(spec_path)
|
||||
# Load OpenAPI spec (async to avoid "called from within a running event loop")
|
||||
spec = await load_openapi_spec_async(spec_path)
|
||||
|
||||
# Use base_url from config if provided, otherwise extract from spec
|
||||
if not base_url:
|
||||
|
|
|
|||
|
|
@ -3,6 +3,8 @@ This module is used to generate MCP tools from OpenAPI specs.
|
|||
"""
|
||||
|
||||
import json
|
||||
import asyncio
|
||||
import os
|
||||
from pathlib import PurePosixPath
|
||||
from typing import Any, Dict, Optional
|
||||
from urllib.parse import quote
|
||||
|
|
@ -45,8 +47,36 @@ def _sanitize_path_parameter_value(param_value: Any, param_name: str) -> str:
|
|||
|
||||
|
||||
def load_openapi_spec(filepath: str) -> Dict[str, Any]:
|
||||
"""Load OpenAPI specification from JSON file."""
|
||||
with open(filepath, "r") as f:
|
||||
"""
|
||||
Sync wrapper. For URL specs, use the shared/custom MCP httpx client.
|
||||
"""
|
||||
try:
|
||||
# If we're already inside an event loop, prefer the async function.
|
||||
asyncio.get_running_loop()
|
||||
raise RuntimeError(
|
||||
"load_openapi_spec() was called from within a running event loop. "
|
||||
"Use 'await load_openapi_spec_async(...)' instead."
|
||||
)
|
||||
except RuntimeError as e:
|
||||
# "no running event loop" is fine; other RuntimeErrors we re-raise
|
||||
if "no running event loop" not in str(e).lower():
|
||||
raise
|
||||
return asyncio.run(load_openapi_spec_async(filepath))
|
||||
|
||||
async def load_openapi_spec_async(filepath: str) -> Dict[str, Any]:
|
||||
if filepath.startswith("http://") or filepath.startswith("https://"):
|
||||
client = get_async_httpx_client(llm_provider=httpxSpecialProvider.MCP)
|
||||
# NOTE: do not close shared client if get_async_httpx_client returns a shared singleton.
|
||||
# If it returns a new client each time, consider wrapping it in an async context manager.
|
||||
r = await client.get(filepath)
|
||||
r.raise_for_status()
|
||||
return r.json()
|
||||
|
||||
# fallback: local file
|
||||
# Local filesystem path
|
||||
if not os.path.exists(filepath):
|
||||
raise FileNotFoundError(f"OpenAPI spec not found at {filepath}")
|
||||
with open(filepath, "r", encoding="utf-8") as f:
|
||||
return json.load(f)
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
import importlib
|
||||
from datetime import datetime
|
||||
from typing import Dict, List, Optional, Union
|
||||
from typing import Any, Awaitable, Callable, Dict, List, Optional, Union
|
||||
|
||||
from fastapi import APIRouter, Depends, HTTPException, Query, Request
|
||||
|
||||
|
|
@ -501,24 +501,50 @@ if MCP_AVAILABLE:
|
|||
NewMCPServerRequest,
|
||||
)
|
||||
|
||||
def _extract_credentials(
|
||||
request: NewMCPServerRequest,
|
||||
) -> tuple:
|
||||
"""
|
||||
Extract OAuth credentials from the nested ``request.credentials`` dict.
|
||||
|
||||
Returns:
|
||||
(client_id, client_secret, scopes) — any value may be ``None``.
|
||||
"""
|
||||
creds = request.credentials if isinstance(request.credentials, dict) else {}
|
||||
client_id: Optional[str] = creds.get("client_id")
|
||||
client_secret: Optional[str] = creds.get("client_secret")
|
||||
scopes_raw = creds.get("scopes")
|
||||
scopes: Optional[List[str]] = scopes_raw if isinstance(scopes_raw, list) else None
|
||||
return client_id, client_secret, scopes
|
||||
|
||||
async def _execute_with_mcp_client(
|
||||
request: NewMCPServerRequest,
|
||||
operation,
|
||||
operation: Callable[..., Awaitable[Any]],
|
||||
mcp_auth_header: Optional[Union[str, Dict[str, str]]] = None,
|
||||
oauth2_headers: Optional[Dict[str, str]] = None,
|
||||
raw_headers: Optional[Dict[str, str]] = None,
|
||||
):
|
||||
) -> dict:
|
||||
"""
|
||||
Common helper to create MCP client, execute operation, and ensure proper cleanup.
|
||||
Create a temporary MCP client from *request*, run *operation*, and return the result.
|
||||
|
||||
For M2M OAuth servers (those with ``client_id``, ``client_secret``, and
|
||||
``token_url``), the incoming ``oauth2_headers`` are dropped so that
|
||||
``resolve_mcp_auth`` can auto-fetch a token via ``client_credentials``.
|
||||
|
||||
Args:
|
||||
request: MCP server configuration
|
||||
operation: Async function that takes a client and returns the operation result
|
||||
request: MCP server configuration submitted by the UI.
|
||||
operation: Async callable that receives the created client and returns a result dict.
|
||||
mcp_auth_header: Pre-resolved credential header (API-key / bearer token).
|
||||
oauth2_headers: Headers extracted from the incoming request (may contain the
|
||||
litellm API key — must NOT be forwarded for M2M servers).
|
||||
raw_headers: Raw request headers forwarded for stdio env construction.
|
||||
|
||||
Returns:
|
||||
Operation result or error response
|
||||
The dict returned by *operation*, or an error dict on failure.
|
||||
"""
|
||||
try:
|
||||
client_id, client_secret, scopes = _extract_credentials(request)
|
||||
|
||||
server_model = MCPServer(
|
||||
server_id=request.server_id or "",
|
||||
name=request.alias or request.server_name or "",
|
||||
|
|
@ -530,14 +556,26 @@ if MCP_AVAILABLE:
|
|||
args=request.args,
|
||||
env=request.env,
|
||||
static_headers=request.static_headers,
|
||||
client_id=client_id,
|
||||
client_secret=client_secret,
|
||||
token_url=request.token_url,
|
||||
scopes=scopes,
|
||||
authorization_url=request.authorization_url,
|
||||
registration_url=request.registration_url,
|
||||
)
|
||||
|
||||
stdio_env = global_mcp_server_manager._build_stdio_env(
|
||||
server_model, raw_headers
|
||||
)
|
||||
|
||||
# For M2M OAuth servers, drop the incoming Authorization header so that
|
||||
# resolve_mcp_auth can auto-fetch a token via client_credentials.
|
||||
effective_oauth2_headers = (
|
||||
None if server_model.has_client_credentials else oauth2_headers
|
||||
)
|
||||
|
||||
merged_headers = merge_mcp_headers(
|
||||
extra_headers=oauth2_headers,
|
||||
extra_headers=effective_oauth2_headers,
|
||||
static_headers=request.static_headers,
|
||||
)
|
||||
|
||||
|
|
@ -550,11 +588,14 @@ if MCP_AVAILABLE:
|
|||
|
||||
return await operation(client)
|
||||
|
||||
except Exception as e:
|
||||
verbose_logger.error(f"Error in MCP operation: {e}", exc_info=True)
|
||||
except (KeyboardInterrupt, SystemExit):
|
||||
raise
|
||||
except BaseException as e:
|
||||
verbose_logger.error("Error in MCP operation: %s", e, exc_info=True)
|
||||
return {
|
||||
"status": "error",
|
||||
"message": "An internal error has occurred while testing the MCP server.",
|
||||
"error": True,
|
||||
"message": "Failed to connect to MCP server. Check proxy logs for details.",
|
||||
}
|
||||
|
||||
@router.post("/test/connection", dependencies=[Depends(user_api_key_auth)])
|
||||
|
|
|
|||
|
|
@ -31,6 +31,9 @@ from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLogging
|
|||
from litellm.proxy._experimental.mcp_server.auth.user_api_key_auth_mcp import (
|
||||
MCPRequestHandler,
|
||||
)
|
||||
from litellm.proxy._experimental.mcp_server.discoverable_endpoints import (
|
||||
get_request_base_url,
|
||||
)
|
||||
from litellm.proxy._experimental.mcp_server.utils import (
|
||||
LITELLM_MCP_SERVER_DESCRIPTION,
|
||||
LITELLM_MCP_SERVER_NAME,
|
||||
|
|
@ -1972,7 +1975,7 @@ if MCP_AVAILABLE:
|
|||
)
|
||||
if server and server.auth_type == MCPAuth.oauth2 and not oauth2_headers:
|
||||
request = StarletteRequest(scope)
|
||||
base_url = str(request.base_url).rstrip("/")
|
||||
base_url = get_request_base_url(request)
|
||||
|
||||
authorization_uri = (
|
||||
f"Bearer authorization_uri="
|
||||
|
|
|
|||
|
|
@ -420,6 +420,8 @@ class LiteLLMRoutes(enum.Enum):
|
|||
"/mcp/tools",
|
||||
"/mcp/tools/list",
|
||||
"/mcp/tools/call",
|
||||
# Read-only MCP discovery endpoint (virtual keys may be allowed here)
|
||||
"/v1/mcp/server",
|
||||
]
|
||||
|
||||
agent_routes = [
|
||||
|
|
@ -845,9 +847,9 @@ class GenerateRequestBase(LiteLLMPydanticObjectBase):
|
|||
allowed_cache_controls: Optional[list] = []
|
||||
config: Optional[dict] = {}
|
||||
permissions: Optional[dict] = {}
|
||||
model_max_budget: Optional[
|
||||
dict
|
||||
] = {} # {"gpt-4": 5.0, "gpt-3.5-turbo": 5.0}, defaults to {}
|
||||
model_max_budget: Optional[dict] = (
|
||||
{}
|
||||
) # {"gpt-4": 5.0, "gpt-3.5-turbo": 5.0}, defaults to {}
|
||||
|
||||
model_config = ConfigDict(protected_namespaces=())
|
||||
model_rpm_limit: Optional[dict] = None
|
||||
|
|
@ -1396,12 +1398,12 @@ class NewCustomerRequest(BudgetNewRequest):
|
|||
blocked: bool = False # allow/disallow requests for this end-user
|
||||
budget_id: Optional[str] = None # give either a budget_id or max_budget
|
||||
spend: Optional[float] = None
|
||||
allowed_model_region: Optional[
|
||||
AllowedModelRegion
|
||||
] = None # require all user requests to use models in this specific region
|
||||
default_model: Optional[
|
||||
str
|
||||
] = None # if no equivalent model in allowed region - default all requests to this model
|
||||
allowed_model_region: Optional[AllowedModelRegion] = (
|
||||
None # require all user requests to use models in this specific region
|
||||
)
|
||||
default_model: Optional[str] = (
|
||||
None # if no equivalent model in allowed region - default all requests to this model
|
||||
)
|
||||
|
||||
@model_validator(mode="before")
|
||||
@classmethod
|
||||
|
|
@ -1423,12 +1425,12 @@ class UpdateCustomerRequest(LiteLLMPydanticObjectBase):
|
|||
blocked: bool = False # allow/disallow requests for this end-user
|
||||
max_budget: Optional[float] = None
|
||||
budget_id: Optional[str] = None # give either a budget_id or max_budget
|
||||
allowed_model_region: Optional[
|
||||
AllowedModelRegion
|
||||
] = None # require all user requests to use models in this specific region
|
||||
default_model: Optional[
|
||||
str
|
||||
] = None # if no equivalent model in allowed region - default all requests to this model
|
||||
allowed_model_region: Optional[AllowedModelRegion] = (
|
||||
None # require all user requests to use models in this specific region
|
||||
)
|
||||
default_model: Optional[str] = (
|
||||
None # if no equivalent model in allowed region - default all requests to this model
|
||||
)
|
||||
|
||||
|
||||
class DeleteCustomerRequest(LiteLLMPydanticObjectBase):
|
||||
|
|
@ -1516,15 +1518,15 @@ class NewTeamRequest(TeamBase):
|
|||
] = None # raise an error if 'guaranteed_throughput' is set and we're overallocating tpm
|
||||
|
||||
model_tpm_limit: Optional[Dict[str, int]] = None
|
||||
team_member_budget: Optional[
|
||||
float
|
||||
] = None # allow user to set a budget for all team members
|
||||
team_member_rpm_limit: Optional[
|
||||
int
|
||||
] = None # allow user to set RPM limit for all team members
|
||||
team_member_tpm_limit: Optional[
|
||||
int
|
||||
] = None # allow user to set TPM limit for all team members
|
||||
team_member_budget: Optional[float] = (
|
||||
None # allow user to set a budget for all team members
|
||||
)
|
||||
team_member_rpm_limit: Optional[int] = (
|
||||
None # allow user to set RPM limit for all team members
|
||||
)
|
||||
team_member_tpm_limit: Optional[int] = (
|
||||
None # allow user to set TPM limit for all team members
|
||||
)
|
||||
team_member_key_duration: Optional[str] = None # e.g. "1d", "1w", "1m"
|
||||
allowed_vector_store_indexes: Optional[List[AllowedVectorStoreIndexItem]] = None
|
||||
|
||||
|
|
@ -1615,9 +1617,9 @@ class BlockKeyRequest(LiteLLMPydanticObjectBase):
|
|||
|
||||
class AddTeamCallback(LiteLLMPydanticObjectBase):
|
||||
callback_name: str
|
||||
callback_type: Optional[
|
||||
Literal["success", "failure", "success_and_failure"]
|
||||
] = "success_and_failure"
|
||||
callback_type: Optional[Literal["success", "failure", "success_and_failure"]] = (
|
||||
"success_and_failure"
|
||||
)
|
||||
callback_vars: Dict[str, str]
|
||||
|
||||
@model_validator(mode="before")
|
||||
|
|
@ -1908,6 +1910,10 @@ class PassThroughGenericEndpoint(LiteLLMPydanticObjectBase):
|
|||
default=None,
|
||||
description="Guardrails configuration for this passthrough endpoint. Dict keys are guardrail names, values are optional settings for field targeting. When set, all org/team/key level guardrails will also execute. Defaults to None (no guardrails execute).",
|
||||
)
|
||||
is_from_config: bool = Field(
|
||||
default=False,
|
||||
description="True if this endpoint is defined in the config file, False if from DB. Config-defined endpoints cannot be edited via the UI.",
|
||||
)
|
||||
|
||||
|
||||
class PassThroughEndpointResponse(LiteLLMPydanticObjectBase):
|
||||
|
|
@ -1945,9 +1951,9 @@ class ConfigList(LiteLLMPydanticObjectBase):
|
|||
stored_in_db: Optional[bool]
|
||||
field_default_value: Any
|
||||
premium_field: bool = False
|
||||
nested_fields: Optional[
|
||||
List[FieldDetail]
|
||||
] = None # For nested dictionary or Pydantic fields
|
||||
nested_fields: Optional[List[FieldDetail]] = (
|
||||
None # For nested dictionary or Pydantic fields
|
||||
)
|
||||
|
||||
|
||||
class UserHeaderMapping(LiteLLMPydanticObjectBase):
|
||||
|
|
@ -2386,9 +2392,9 @@ class LiteLLM_OrganizationMembershipTable(LiteLLMPydanticObjectBase):
|
|||
budget_id: Optional[str] = None
|
||||
created_at: datetime
|
||||
updated_at: datetime
|
||||
user: Optional[
|
||||
Any
|
||||
] = None # You might want to replace 'Any' with a more specific type if available
|
||||
user: Optional[Any] = (
|
||||
None # You might want to replace 'Any' with a more specific type if available
|
||||
)
|
||||
litellm_budget_table: Optional[LiteLLM_BudgetTable] = None
|
||||
|
||||
model_config = ConfigDict(protected_namespaces=())
|
||||
|
|
@ -3364,9 +3370,9 @@ class TeamModelDeleteRequest(BaseModel):
|
|||
# Organization Member Requests
|
||||
class OrganizationMemberAddRequest(OrgMemberAddRequest):
|
||||
organization_id: str
|
||||
max_budget_in_organization: Optional[
|
||||
float
|
||||
] = None # Users max budget within the organization
|
||||
max_budget_in_organization: Optional[float] = (
|
||||
None # Users max budget within the organization
|
||||
)
|
||||
|
||||
|
||||
class OrganizationMemberDeleteRequest(MemberDeleteRequest):
|
||||
|
|
@ -3584,9 +3590,9 @@ class ProviderBudgetResponse(LiteLLMPydanticObjectBase):
|
|||
Maps provider names to their budget configs.
|
||||
"""
|
||||
|
||||
providers: Dict[
|
||||
str, ProviderBudgetResponseObject
|
||||
] = {} # Dictionary mapping provider names to their budget configurations
|
||||
providers: Dict[str, ProviderBudgetResponseObject] = (
|
||||
{}
|
||||
) # Dictionary mapping provider names to their budget configurations
|
||||
|
||||
|
||||
class ProxyStateVariables(TypedDict):
|
||||
|
|
@ -3729,9 +3735,9 @@ class LiteLLM_JWTAuth(LiteLLMPydanticObjectBase):
|
|||
enforce_rbac: bool = False
|
||||
roles_jwt_field: Optional[str] = None # v2 on role mappings
|
||||
role_mappings: Optional[List[RoleMapping]] = None
|
||||
object_id_jwt_field: Optional[
|
||||
str
|
||||
] = None # can be either user / team, inferred from the role mapping
|
||||
object_id_jwt_field: Optional[str] = (
|
||||
None # can be either user / team, inferred from the role mapping
|
||||
)
|
||||
scope_mappings: Optional[List[ScopeMapping]] = None
|
||||
enforce_scope_based_access: bool = False
|
||||
enforce_team_based_model_access: bool = False
|
||||
|
|
|
|||
|
|
@ -8,6 +8,7 @@ Returns a UserAPIKeyAuth object if the API key is valid
|
|||
"""
|
||||
|
||||
import asyncio
|
||||
import re
|
||||
import secrets
|
||||
from datetime import datetime, timezone
|
||||
from typing import List, Optional, Tuple, cast
|
||||
|
|
@ -115,6 +116,18 @@ def _get_bearer_token_or_received_api_key(api_key: str) -> str:
|
|||
api_key = api_key.replace("Basic ", "") # handle langfuse input
|
||||
elif api_key.startswith("bearer "):
|
||||
api_key = api_key.replace("bearer ", "")
|
||||
elif api_key.startswith("AWS4-HMAC-SHA256"):
|
||||
# Handle AWS Signature V4 format from LangChain
|
||||
# Format: AWS4-HMAC-SHA256 Credential=Bearer sk-12345/date/region/service/aws4_request, SignedHeaders=..., Signature=...
|
||||
# Extract the Bearer token from the Credential field
|
||||
match = re.search(r'Credential=Bearer\s+([^/\s,]+)', api_key)
|
||||
if match:
|
||||
api_key = match.group(1)
|
||||
else:
|
||||
# If no Bearer token found in Credential, try to extract just the credential value
|
||||
match = re.search(r'Credential=([^/\s,]+)', api_key)
|
||||
if match:
|
||||
api_key = match.group(1)
|
||||
|
||||
return api_key
|
||||
|
||||
|
|
@ -128,6 +141,20 @@ def _get_bearer_token(
|
|||
api_key = api_key.replace("Basic ", "") # handle langfuse input
|
||||
elif api_key.startswith("bearer "):
|
||||
api_key = api_key.replace("bearer ", "")
|
||||
elif api_key.startswith("AWS4-HMAC-SHA256"):
|
||||
# Handle AWS Signature V4 format from LangChain
|
||||
# Format: AWS4-HMAC-SHA256 Credential=Bearer sk-12345/date/region/service/aws4_request, SignedHeaders=..., Signature=...
|
||||
# Extract the Bearer token from the Credential field
|
||||
match = re.search(r'Credential=Bearer\s+([^/\s,]+)', api_key)
|
||||
if match:
|
||||
api_key = match.group(1)
|
||||
else:
|
||||
# If no Bearer token found in Credential, try to extract just the credential value
|
||||
match = re.search(r'Credential=([^/\s,]+)', api_key)
|
||||
if match:
|
||||
api_key = match.group(1)
|
||||
else:
|
||||
api_key = ""
|
||||
else:
|
||||
api_key = ""
|
||||
return api_key
|
||||
|
|
|
|||
|
|
@ -24,9 +24,12 @@ async def custom_sso_handler(userIDPInfo: OpenID) -> SSOUserDefinedValues:
|
|||
print(f"userIDPInfo: {userIDPInfo}") # noqa
|
||||
|
||||
if userIDPInfo.id is None:
|
||||
raise ValueError(
|
||||
f"No ID found for user. userIDPInfo.id is None {userIDPInfo}"
|
||||
)
|
||||
raise ValueError(f"No ID found for user. userIDPInfo.id is None {userIDPInfo}")
|
||||
|
||||
# Access extra fields from the IDP response (requires GENERIC_USER_EXTRA_ATTRIBUTES env var)
|
||||
# Example: Set GENERIC_USER_EXTRA_ATTRIBUTES="group,NTID,domain" to capture these fields
|
||||
# extra_fields = getattr(userIDPInfo, 'extra_fields', None) or {}
|
||||
# user_groups = extra_fields.get("group", [])
|
||||
|
||||
# check if user exists in litellm proxy DB
|
||||
_user_info = await user_info(user_id=userIDPInfo.id)
|
||||
|
|
|
|||
|
|
@ -10,14 +10,18 @@ from litellm._service_logger import ServiceLogging
|
|||
service_logger_obj = (
|
||||
ServiceLogging()
|
||||
) # used for tracking metrics for In memory buffer, redis buffer, pod lock manager
|
||||
from litellm.constants import MAX_IN_MEMORY_QUEUE_FLUSH_COUNT, MAX_SIZE_IN_MEMORY_QUEUE
|
||||
from litellm.constants import (
|
||||
LITELLM_ASYNCIO_QUEUE_MAXSIZE,
|
||||
MAX_IN_MEMORY_QUEUE_FLUSH_COUNT,
|
||||
MAX_SIZE_IN_MEMORY_QUEUE,
|
||||
)
|
||||
|
||||
|
||||
class BaseUpdateQueue:
|
||||
"""Base class for in memory buffer for database transactions"""
|
||||
|
||||
def __init__(self):
|
||||
self.update_queue = asyncio.Queue()
|
||||
self.update_queue = asyncio.Queue(maxsize=LITELLM_ASYNCIO_QUEUE_MAXSIZE)
|
||||
self.MAX_SIZE_IN_MEMORY_QUEUE = MAX_SIZE_IN_MEMORY_QUEUE
|
||||
|
||||
async def add_update(self, update):
|
||||
|
|
|
|||
|
|
@ -3,6 +3,7 @@ from copy import deepcopy
|
|||
from typing import Dict, List, Optional
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.constants import LITELLM_ASYNCIO_QUEUE_MAXSIZE
|
||||
from litellm.proxy._types import BaseDailySpendTransaction
|
||||
from litellm.proxy.db.db_transaction_queue.base_update_queue import (
|
||||
BaseUpdateQueue,
|
||||
|
|
@ -54,7 +55,7 @@ class DailySpendUpdateQueue(BaseUpdateQueue):
|
|||
def __init__(self):
|
||||
super().__init__()
|
||||
self.update_queue: asyncio.Queue[Dict[str, BaseDailySpendTransaction]] = (
|
||||
asyncio.Queue()
|
||||
asyncio.Queue(maxsize=LITELLM_ASYNCIO_QUEUE_MAXSIZE)
|
||||
)
|
||||
|
||||
async def add_update(self, update: Dict[str, BaseDailySpendTransaction]):
|
||||
|
|
|
|||
|
|
@ -2,6 +2,7 @@ import asyncio
|
|||
from typing import Dict, List, Optional
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.constants import LITELLM_ASYNCIO_QUEUE_MAXSIZE
|
||||
from litellm.proxy._types import (
|
||||
DBSpendUpdateTransactions,
|
||||
Litellm_EntityType,
|
||||
|
|
@ -21,7 +22,9 @@ class SpendUpdateQueue(BaseUpdateQueue):
|
|||
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.update_queue: asyncio.Queue[SpendUpdateQueueItem] = asyncio.Queue()
|
||||
self.update_queue: asyncio.Queue[SpendUpdateQueueItem] = asyncio.Queue(
|
||||
maxsize=LITELLM_ASYNCIO_QUEUE_MAXSIZE
|
||||
)
|
||||
|
||||
async def flush_and_get_aggregated_db_spend_update_transactions(
|
||||
self,
|
||||
|
|
|
|||
|
|
@ -15,6 +15,7 @@ from litellm.proxy._types import UserAPIKeyAuth
|
|||
from litellm.proxy.auth.user_api_key_auth import user_api_key_auth
|
||||
from litellm.proxy.guardrails.guardrail_registry import GuardrailRegistry
|
||||
from litellm.types.guardrails import (
|
||||
BaseLitellmParams,
|
||||
PII_ENTITY_CATEGORIES_MAP,
|
||||
ApplyGuardrailRequest,
|
||||
ApplyGuardrailResponse,
|
||||
|
|
@ -150,6 +151,7 @@ async def list_guardrails_v2():
|
|||
}
|
||||
```
|
||||
"""
|
||||
from litellm.litellm_core_utils.litellm_logging import _get_masked_values
|
||||
from litellm.proxy.guardrails.guardrail_registry import IN_MEMORY_GUARDRAIL_HANDLER
|
||||
from litellm.proxy.proxy_server import prisma_client
|
||||
|
||||
|
|
@ -164,11 +166,29 @@ async def list_guardrails_v2():
|
|||
guardrail_configs: List[GuardrailInfoResponse] = []
|
||||
seen_guardrail_ids = set()
|
||||
for guardrail in guardrails:
|
||||
litellm_params: Optional[Union[LitellmParams, dict]] = guardrail.get(
|
||||
"litellm_params"
|
||||
)
|
||||
litellm_params_dict = (
|
||||
litellm_params.model_dump(exclude_none=True)
|
||||
if isinstance(litellm_params, LitellmParams)
|
||||
else litellm_params
|
||||
) or {}
|
||||
masked_litellm_params_dict = _get_masked_values(
|
||||
litellm_params_dict,
|
||||
unmasked_length=4,
|
||||
number_of_asterisks=4,
|
||||
)
|
||||
masked_litellm_params = (
|
||||
BaseLitellmParams(**masked_litellm_params_dict)
|
||||
if masked_litellm_params_dict
|
||||
else None
|
||||
)
|
||||
guardrail_configs.append(
|
||||
GuardrailInfoResponse(
|
||||
guardrail_id=guardrail.get("guardrail_id"),
|
||||
guardrail_name=guardrail.get("guardrail_name"),
|
||||
litellm_params=guardrail.get("litellm_params"),
|
||||
litellm_params=masked_litellm_params,
|
||||
guardrail_info=guardrail.get("guardrail_info"),
|
||||
created_at=guardrail.get("created_at"),
|
||||
updated_at=guardrail.get("updated_at"),
|
||||
|
|
@ -182,11 +202,27 @@ async def list_guardrails_v2():
|
|||
for guardrail in in_memory_guardrails:
|
||||
# only add guardrails that are not in DB guardrail list already
|
||||
if guardrail.get("guardrail_id") not in seen_guardrail_ids:
|
||||
in_memory_litellm_params_raw = guardrail.get("litellm_params")
|
||||
in_memory_litellm_params_dict = (
|
||||
in_memory_litellm_params_raw.model_dump(exclude_none=True)
|
||||
if isinstance(in_memory_litellm_params_raw, LitellmParams)
|
||||
else in_memory_litellm_params_raw
|
||||
) or {}
|
||||
masked_in_memory_litellm_params = _get_masked_values(
|
||||
in_memory_litellm_params_dict,
|
||||
unmasked_length=4,
|
||||
number_of_asterisks=4,
|
||||
)
|
||||
masked_in_memory_litellm_params_typed = (
|
||||
BaseLitellmParams(**masked_in_memory_litellm_params)
|
||||
if masked_in_memory_litellm_params
|
||||
else None
|
||||
)
|
||||
guardrail_configs.append(
|
||||
GuardrailInfoResponse(
|
||||
guardrail_id=guardrail.get("guardrail_id"),
|
||||
guardrail_name=guardrail.get("guardrail_name"),
|
||||
litellm_params=dict(guardrail.get("litellm_params") or {}),
|
||||
litellm_params=masked_in_memory_litellm_params_typed,
|
||||
guardrail_info=dict(guardrail.get("guardrail_info") or {}),
|
||||
guardrail_definition_location="config",
|
||||
)
|
||||
|
|
@ -666,11 +702,16 @@ async def get_guardrail_info(guardrail_id: str):
|
|||
unmasked_length=4,
|
||||
number_of_asterisks=4,
|
||||
)
|
||||
masked_litellm_params = (
|
||||
BaseLitellmParams(**masked_litellm_params_dict)
|
||||
if masked_litellm_params_dict
|
||||
else None
|
||||
)
|
||||
|
||||
return GuardrailInfoResponse(
|
||||
guardrail_id=result.get("guardrail_id"),
|
||||
guardrail_name=result.get("guardrail_name"),
|
||||
litellm_params=masked_litellm_params_dict,
|
||||
litellm_params=masked_litellm_params,
|
||||
guardrail_info=dict(result.get("guardrail_info") or {}),
|
||||
created_at=result.get("created_at"),
|
||||
updated_at=result.get("updated_at"),
|
||||
|
|
|
|||
|
|
@ -461,12 +461,37 @@ class BedrockGuardrail(CustomGuardrail, BaseAWSLLM):
|
|||
data=prepared_request.body, # type: ignore
|
||||
headers=prepared_request.headers, # type: ignore
|
||||
)
|
||||
except HTTPException:
|
||||
# Propagate HTTPException (e.g. from non-200 path) as-is
|
||||
raise
|
||||
except Exception as e:
|
||||
# If this is an HTTP error with a response body (e.g. httpx.HTTPStatusError),
|
||||
# extract the AWS error message and propagate it
|
||||
response = getattr(e, "response", None)
|
||||
if isinstance(response, httpx.Response):
|
||||
try:
|
||||
status_code, detail_message = (
|
||||
self._parse_bedrock_guardrail_error_response(response)
|
||||
)
|
||||
self.add_standard_logging_guardrail_information_to_request_data(
|
||||
guardrail_provider=self.guardrail_provider,
|
||||
guardrail_json_response={"error": detail_message},
|
||||
request_data=request_data or {},
|
||||
guardrail_status="guardrail_failed_to_respond",
|
||||
start_time=start_time.timestamp(),
|
||||
end_time=datetime.now().timestamp(),
|
||||
duration=(datetime.now() - start_time).total_seconds(),
|
||||
event_type=event_type,
|
||||
)
|
||||
raise HTTPException(
|
||||
status_code=status_code, detail=detail_message
|
||||
) from e
|
||||
except HTTPException:
|
||||
raise
|
||||
# Endpoint down, timeout, or other HTTP/network errors
|
||||
verbose_proxy_logger.error(
|
||||
"Bedrock AI: failed to make guardrail request: %s", str(e)
|
||||
)
|
||||
# Add guardrail information with failure status
|
||||
self.add_standard_logging_guardrail_information_to_request_data(
|
||||
guardrail_provider=self.guardrail_provider,
|
||||
guardrail_json_response={"error": str(e)},
|
||||
|
|
@ -477,7 +502,6 @@ class BedrockGuardrail(CustomGuardrail, BaseAWSLLM):
|
|||
duration=(datetime.now() - start_time).total_seconds(),
|
||||
event_type=event_type,
|
||||
)
|
||||
# Re-raise the exception to maintain existing behavior
|
||||
raise
|
||||
|
||||
#########################################################
|
||||
|
|
@ -509,11 +533,15 @@ class BedrockGuardrail(CustomGuardrail, BaseAWSLLM):
|
|||
bedrock_guardrail_response
|
||||
)
|
||||
else:
|
||||
status_code, detail_message = self._parse_bedrock_guardrail_error_response(
|
||||
httpx_response
|
||||
)
|
||||
verbose_proxy_logger.error(
|
||||
"Bedrock AI: error in response. Status code: %s, response: %s",
|
||||
httpx_response.status_code,
|
||||
httpx_response.text,
|
||||
)
|
||||
raise HTTPException(status_code=status_code, detail=detail_message)
|
||||
|
||||
return bedrock_guardrail_response
|
||||
|
||||
|
|
@ -579,6 +607,34 @@ class BedrockGuardrail(CustomGuardrail, BaseAWSLLM):
|
|||
return "success"
|
||||
return "guardrail_failed_to_respond"
|
||||
|
||||
def _parse_bedrock_guardrail_error_response(
|
||||
self, response: httpx.Response
|
||||
) -> Tuple[int, str]:
|
||||
"""
|
||||
Parse AWS Bedrock guardrail error response body to extract status code and message.
|
||||
|
||||
AWS may return shapes like {"message": "..."} or {"error": {"message": "..."}}.
|
||||
Returns (status_code, message) for use in HTTPException.
|
||||
"""
|
||||
status_code = response.status_code
|
||||
message = "Bedrock guardrail request failed"
|
||||
try:
|
||||
body = response.json()
|
||||
except Exception:
|
||||
text = getattr(response, "text", None) or ""
|
||||
if isinstance(text, str) and text.strip():
|
||||
return (status_code, text.strip())
|
||||
return (status_code, message)
|
||||
if isinstance(body, dict):
|
||||
if isinstance(body.get("message"), str):
|
||||
return (status_code, body["message"])
|
||||
err = body.get("error")
|
||||
if isinstance(err, dict) and isinstance(err.get("message"), str):
|
||||
return (status_code, err["message"])
|
||||
if isinstance(err, str):
|
||||
return (status_code, err)
|
||||
return (status_code, message)
|
||||
|
||||
def _get_http_exception_for_blocked_guardrail(
|
||||
self, response: BedrockGuardrailResponse
|
||||
) -> Union[HTTPException, GuardrailInterventionNormalStringError]:
|
||||
|
|
@ -739,9 +795,9 @@ class BedrockGuardrail(CustomGuardrail, BaseAWSLLM):
|
|||
#########################################################
|
||||
########## 1. Make the Bedrock API request ##########
|
||||
#########################################################
|
||||
bedrock_guardrail_response: Optional[
|
||||
Union[BedrockGuardrailResponse, str]
|
||||
] = None
|
||||
bedrock_guardrail_response: Optional[Union[BedrockGuardrailResponse, str]] = (
|
||||
None
|
||||
)
|
||||
try:
|
||||
bedrock_guardrail_response = await self.make_bedrock_api_request(
|
||||
source="INPUT", messages=filtered_messages, request_data=data
|
||||
|
|
@ -811,9 +867,9 @@ class BedrockGuardrail(CustomGuardrail, BaseAWSLLM):
|
|||
#########################################################
|
||||
########## 1. Make the Bedrock API request ##########
|
||||
#########################################################
|
||||
bedrock_guardrail_response: Optional[
|
||||
Union[BedrockGuardrailResponse, str]
|
||||
] = None
|
||||
bedrock_guardrail_response: Optional[Union[BedrockGuardrailResponse, str]] = (
|
||||
None
|
||||
)
|
||||
try:
|
||||
bedrock_guardrail_response = await self.make_bedrock_api_request(
|
||||
source="INPUT", messages=filtered_messages, request_data=data
|
||||
|
|
|
|||
|
|
@ -35,7 +35,10 @@ from typing import TYPE_CHECKING, Any, Dict, Literal, Optional, Type, cast
|
|||
from fastapi import HTTPException
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.integrations.custom_guardrail import CustomGuardrail
|
||||
from litellm.integrations.custom_guardrail import (
|
||||
CustomGuardrail,
|
||||
log_guardrail_information,
|
||||
)
|
||||
from litellm.types.guardrails import GuardrailEventHooks
|
||||
from litellm.types.proxy.guardrails.guardrail_hooks.base import GuardrailConfigModel
|
||||
from litellm.types.utils import GenericGuardrailAPIInputs
|
||||
|
|
@ -179,6 +182,7 @@ class CustomCodeGuardrail(CustomGuardrail):
|
|||
self._compile_error = f"Failed to compile custom code: {e}"
|
||||
raise CustomCodeCompilationError(self._compile_error) from e
|
||||
|
||||
@log_guardrail_information
|
||||
async def apply_guardrail(
|
||||
self,
|
||||
inputs: GenericGuardrailAPIInputs,
|
||||
|
|
|
|||
|
|
@ -23,7 +23,10 @@ import httpx
|
|||
import litellm
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.caching.caching import DualCache
|
||||
from litellm.integrations.custom_guardrail import CustomGuardrail
|
||||
from litellm.integrations.custom_guardrail import (
|
||||
CustomGuardrail,
|
||||
log_guardrail_information,
|
||||
)
|
||||
from litellm.llms.custom_httpx.http_handler import (
|
||||
get_async_httpx_client,
|
||||
httpxSpecialProvider,
|
||||
|
|
@ -483,6 +486,7 @@ class EnkryptAIGuardrails(CustomGuardrail):
|
|||
request_data=data, guardrail_name=self.guardrail_name
|
||||
)
|
||||
|
||||
@log_guardrail_information
|
||||
async def apply_guardrail(
|
||||
self,
|
||||
inputs: "GenericGuardrailAPIInputs",
|
||||
|
|
|
|||
|
|
@ -10,7 +10,10 @@ from typing import TYPE_CHECKING, Any, Dict, Literal, Optional
|
|||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.exceptions import GuardrailRaisedException
|
||||
from litellm.integrations.custom_guardrail import CustomGuardrail
|
||||
from litellm.integrations.custom_guardrail import (
|
||||
CustomGuardrail,
|
||||
log_guardrail_information,
|
||||
)
|
||||
from litellm.llms.custom_httpx.http_handler import (
|
||||
get_async_httpx_client,
|
||||
httpxSpecialProvider,
|
||||
|
|
@ -150,6 +153,7 @@ class GenericGuardrailAPI(CustomGuardrail):
|
|||
|
||||
return result_metadata
|
||||
|
||||
@log_guardrail_information
|
||||
async def apply_guardrail(
|
||||
self,
|
||||
inputs: GenericGuardrailAPIInputs,
|
||||
|
|
|
|||
|
|
@ -9,7 +9,8 @@ from fastapi import HTTPException
|
|||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.integrations.custom_guardrail import (
|
||||
CustomGuardrail,
|
||||
ModifyResponseException
|
||||
ModifyResponseException,
|
||||
log_guardrail_information,
|
||||
)
|
||||
from litellm.litellm_core_utils.safe_json_dumps import safe_dumps
|
||||
from litellm.litellm_core_utils.safe_json_loads import safe_json_loads
|
||||
|
|
@ -108,7 +109,9 @@ class GraySwanGuardrail(CustomGuardrail):
|
|||
self.categories = categories
|
||||
self.policy_id = policy_id
|
||||
self.fail_open = True if fail_open is None else bool(fail_open)
|
||||
self.guardrail_timeout = 30.0 if guardrail_timeout is None else float(guardrail_timeout)
|
||||
self.guardrail_timeout = (
|
||||
30.0 if guardrail_timeout is None else float(guardrail_timeout)
|
||||
)
|
||||
|
||||
# Streaming configuration
|
||||
self.streaming_end_of_stream_only = streaming_end_of_stream_only
|
||||
|
|
@ -155,6 +158,7 @@ class GraySwanGuardrail(CustomGuardrail):
|
|||
# Unified Guardrail Interface (works with ALL endpoints automatically)
|
||||
# ------------------------------------------------------------------
|
||||
|
||||
@log_guardrail_information
|
||||
async def apply_guardrail(
|
||||
self,
|
||||
inputs: GenericGuardrailAPIInputs,
|
||||
|
|
@ -208,7 +212,9 @@ class GraySwanGuardrail(CustomGuardrail):
|
|||
messages = [{"role": role, "content": text} for text in texts]
|
||||
|
||||
# Get dynamic params from request metadata
|
||||
dynamic_body = self.get_guardrail_dynamic_request_body_params(request_data) or {}
|
||||
dynamic_body = (
|
||||
self.get_guardrail_dynamic_request_body_params(request_data) or {}
|
||||
)
|
||||
if dynamic_body:
|
||||
verbose_proxy_logger.debug(
|
||||
"Gray Swan Guardrail: dynamic extra_body=%s", safe_dumps(dynamic_body)
|
||||
|
|
@ -271,12 +277,12 @@ class GraySwanGuardrail(CustomGuardrail):
|
|||
async def run_grayswan_guardrail(self, payload: dict) -> Dict[str, Any]:
|
||||
"""
|
||||
Run the GraySwan guardrail on a payload.
|
||||
|
||||
|
||||
This is a legacy method for testing purposes.
|
||||
|
||||
|
||||
Args:
|
||||
payload: The payload to scan
|
||||
|
||||
|
||||
Returns:
|
||||
Dict containing the GraySwan API response
|
||||
"""
|
||||
|
|
@ -293,11 +299,11 @@ class GraySwanGuardrail(CustomGuardrail):
|
|||
) -> None:
|
||||
"""
|
||||
Legacy method for processing GraySwan API responses.
|
||||
|
||||
|
||||
This method is maintained for backward compatibility with existing tests.
|
||||
It handles the test scenarios where responses need to be processed with
|
||||
knowledge of the request context (pre/during/post call hooks).
|
||||
|
||||
|
||||
Args:
|
||||
response_json: Response from GraySwan API
|
||||
data: Optional request data (for passthrough exceptions)
|
||||
|
|
@ -365,7 +371,10 @@ class GraySwanGuardrail(CustomGuardrail):
|
|||
)
|
||||
|
||||
# If hook_type is provided and in pre/during call, raise exception
|
||||
if hook_type in [GuardrailEventHooks.pre_call, GuardrailEventHooks.during_call]:
|
||||
if hook_type in [
|
||||
GuardrailEventHooks.pre_call,
|
||||
GuardrailEventHooks.during_call,
|
||||
]:
|
||||
# Raise ModifyResponseException to short-circuit LLM call
|
||||
if data is None:
|
||||
data = {}
|
||||
|
|
@ -540,7 +549,9 @@ class GraySwanGuardrail(CustomGuardrail):
|
|||
if isinstance(litellm_metadata, dict) and litellm_metadata:
|
||||
cleaned_litellm_metadata = dict(litellm_metadata)
|
||||
# cleaned_litellm_metadata.pop("user_api_key_auth", None)
|
||||
sanitized = safe_json_loads(safe_dumps(cleaned_litellm_metadata), default={})
|
||||
sanitized = safe_json_loads(
|
||||
safe_dumps(cleaned_litellm_metadata), default={}
|
||||
)
|
||||
if isinstance(sanitized, dict) and sanitized:
|
||||
payload["litellm_metadata"] = sanitized
|
||||
|
||||
|
|
@ -566,7 +577,9 @@ class GraySwanGuardrail(CustomGuardrail):
|
|||
detection_info = detection_info[0]
|
||||
|
||||
# Extract fields from detection_info dict
|
||||
detection_dict: dict = detection_info if isinstance(detection_info, dict) else {}
|
||||
detection_dict: dict = (
|
||||
detection_info if isinstance(detection_info, dict) else {}
|
||||
)
|
||||
violation_score = detection_dict.get("violation_score", 0.0)
|
||||
violated_rules = detection_dict.get("violated_rules", [])
|
||||
mutation = detection_dict.get("mutation", False)
|
||||
|
|
@ -582,7 +595,9 @@ class GraySwanGuardrail(CustomGuardrail):
|
|||
if violated_rules:
|
||||
formatted_rules = self._format_violated_rules(violated_rules)
|
||||
if formatted_rules:
|
||||
message_parts.append(f"It was violating the rule(s): {formatted_rules}.")
|
||||
message_parts.append(
|
||||
f"It was violating the rule(s): {formatted_rules}."
|
||||
)
|
||||
|
||||
if mutation:
|
||||
message_parts.append(
|
||||
|
|
@ -590,9 +605,7 @@ class GraySwanGuardrail(CustomGuardrail):
|
|||
)
|
||||
|
||||
if ipi:
|
||||
message_parts.append(
|
||||
"Indirect Prompt Injection was DETECTED."
|
||||
)
|
||||
message_parts.append("Indirect Prompt Injection was DETECTED.")
|
||||
|
||||
return "\n".join(message_parts)
|
||||
|
||||
|
|
|
|||
|
|
@ -10,7 +10,10 @@ from httpx import HTTPStatusError
|
|||
from requests.auth import HTTPBasicAuth
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.integrations.custom_guardrail import CustomGuardrail
|
||||
from litellm.integrations.custom_guardrail import (
|
||||
CustomGuardrail,
|
||||
log_guardrail_information,
|
||||
)
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj
|
||||
from litellm.llms.custom_httpx.http_handler import (
|
||||
get_async_httpx_client,
|
||||
|
|
@ -110,6 +113,7 @@ class HiddenlayerGuardrail(CustomGuardrail):
|
|||
)
|
||||
super().__init__(**kwargs)
|
||||
|
||||
@log_guardrail_information
|
||||
async def apply_guardrail(
|
||||
self,
|
||||
inputs: GenericGuardrailAPIInputs,
|
||||
|
|
|
|||
|
|
@ -28,7 +28,10 @@ from fastapi import HTTPException
|
|||
|
||||
from litellm import Router
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.integrations.custom_guardrail import CustomGuardrail
|
||||
from litellm.integrations.custom_guardrail import (
|
||||
CustomGuardrail,
|
||||
log_guardrail_information,
|
||||
)
|
||||
from litellm.proxy._types import UserAPIKeyAuth
|
||||
from litellm.types.utils import ModelResponseStream
|
||||
|
||||
|
|
@ -50,6 +53,7 @@ from litellm.types.proxy.guardrails.guardrail_hooks.litellm_content_filter impor
|
|||
ContentFilterDetection,
|
||||
PatternDetection,
|
||||
)
|
||||
|
||||
from .patterns import PATTERN_EXTRA_CONFIG, get_compiled_pattern
|
||||
|
||||
MAX_KEYWORD_VALUE_GAP_WORDS = 1
|
||||
|
|
@ -168,9 +172,9 @@ class ContentFilterGuardrail(CustomGuardrail):
|
|||
self.image_model = image_model
|
||||
# Store loaded categories
|
||||
self.loaded_categories: Dict[str, CategoryConfig] = {}
|
||||
self.category_keywords: Dict[
|
||||
str, Tuple[str, str, ContentFilterAction]
|
||||
] = {} # keyword -> (category, severity, action)
|
||||
self.category_keywords: Dict[str, Tuple[str, str, ContentFilterAction]] = (
|
||||
{}
|
||||
) # keyword -> (category, severity, action)
|
||||
|
||||
# Load categories if provided
|
||||
if categories:
|
||||
|
|
@ -994,6 +998,7 @@ class ContentFilterGuardrail(CustomGuardrail):
|
|||
masked_entity_count=masked_entity_count,
|
||||
)
|
||||
|
||||
@log_guardrail_information
|
||||
async def apply_guardrail(
|
||||
self,
|
||||
inputs: "GenericGuardrailAPIInputs",
|
||||
|
|
|
|||
|
|
@ -12,7 +12,10 @@ import httpx
|
|||
from fastapi import HTTPException
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.integrations.custom_guardrail import CustomGuardrail
|
||||
from litellm.integrations.custom_guardrail import (
|
||||
CustomGuardrail,
|
||||
log_guardrail_information,
|
||||
)
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj
|
||||
from litellm.llms.custom_httpx.http_handler import (
|
||||
get_async_httpx_client,
|
||||
|
|
@ -26,7 +29,11 @@ if TYPE_CHECKING:
|
|||
|
||||
class OnyxGuardrail(CustomGuardrail):
|
||||
def __init__(
|
||||
self, api_base: Optional[str] = None, api_key: Optional[str] = None, timeout: Optional[float] = 10.0, **kwargs
|
||||
self,
|
||||
api_base: Optional[str] = None,
|
||||
api_key: Optional[str] = None,
|
||||
timeout: Optional[float] = 10.0,
|
||||
**kwargs,
|
||||
):
|
||||
timeout = timeout or int(os.getenv("ONYX_TIMEOUT", 10.0))
|
||||
self.async_handler = get_async_httpx_client(
|
||||
|
|
@ -79,6 +86,7 @@ class OnyxGuardrail(CustomGuardrail):
|
|||
)
|
||||
return result
|
||||
|
||||
@log_guardrail_information
|
||||
async def apply_guardrail(
|
||||
self,
|
||||
inputs: GenericGuardrailAPIInputs,
|
||||
|
|
|
|||
|
|
@ -58,7 +58,9 @@ class OpenAIModerationGuardrail(OpenAIGuardrailBase, CustomGuardrail):
|
|||
guardrail_name: str,
|
||||
api_key: Optional[str] = None,
|
||||
api_base: Optional[str] = None,
|
||||
model: Optional[Literal["omni-moderation-latest", "text-moderation-latest"]] = None,
|
||||
model: Optional[
|
||||
Literal["omni-moderation-latest", "text-moderation-latest"]
|
||||
] = None,
|
||||
**kwargs,
|
||||
):
|
||||
"""Initialize OpenAI Moderation guardrail handler."""
|
||||
|
|
@ -75,7 +77,7 @@ class OpenAIModerationGuardrail(OpenAIGuardrailBase, CustomGuardrail):
|
|||
supported_event_hooks=supported_event_hooks,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
|
||||
self.async_handler = get_async_httpx_client(
|
||||
llm_provider=httpxSpecialProvider.GuardrailCallback
|
||||
)
|
||||
|
|
@ -83,10 +85,14 @@ class OpenAIModerationGuardrail(OpenAIGuardrailBase, CustomGuardrail):
|
|||
# Store configuration
|
||||
self.api_key = api_key or self._get_api_key()
|
||||
self.api_base = api_base or "https://api.openai.com/v1"
|
||||
self.model: Literal["omni-moderation-latest", "text-moderation-latest"] = model or "omni-moderation-latest"
|
||||
self.model: Literal["omni-moderation-latest", "text-moderation-latest"] = (
|
||||
model or "omni-moderation-latest"
|
||||
)
|
||||
|
||||
if not self.api_key:
|
||||
raise ValueError("OpenAI Moderation: api_key is required. Set OPENAI_API_KEY environment variable or pass it in configuration.")
|
||||
raise ValueError(
|
||||
"OpenAI Moderation: api_key is required. Set OPENAI_API_KEY environment variable or pass it in configuration."
|
||||
)
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
f"Initialized OpenAI Moderation Guardrail: {guardrail_name} with model: {self.model}"
|
||||
|
|
@ -98,7 +104,7 @@ class OpenAIModerationGuardrail(OpenAIGuardrailBase, CustomGuardrail):
|
|||
|
||||
import litellm
|
||||
from litellm.secret_managers.main import get_secret_str
|
||||
|
||||
|
||||
return (
|
||||
os.environ.get("OPENAI_API_KEY")
|
||||
or litellm.api_key
|
||||
|
|
@ -106,21 +112,14 @@ class OpenAIModerationGuardrail(OpenAIGuardrailBase, CustomGuardrail):
|
|||
or get_secret_str("OPENAI_API_KEY")
|
||||
)
|
||||
|
||||
async def async_make_request(
|
||||
self, input_text: str
|
||||
) -> "OpenAIModerationResponse":
|
||||
async def async_make_request(self, input_text: str) -> "OpenAIModerationResponse":
|
||||
"""
|
||||
Make a request to the OpenAI Moderation API.
|
||||
"""
|
||||
request_body = {
|
||||
"model": self.model,
|
||||
"input": input_text
|
||||
}
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
"OpenAI Moderation guard request: %s", request_body
|
||||
)
|
||||
|
||||
request_body = {"model": self.model, "input": input_text}
|
||||
|
||||
verbose_proxy_logger.debug("OpenAI Moderation guard request: %s", request_body)
|
||||
|
||||
response = await self.async_handler.post(
|
||||
url=f"{self.api_base}/moderations",
|
||||
headers={
|
||||
|
|
@ -133,7 +132,7 @@ class OpenAIModerationGuardrail(OpenAIGuardrailBase, CustomGuardrail):
|
|||
verbose_proxy_logger.debug(
|
||||
"OpenAI Moderation guard response: %s", response.json()
|
||||
)
|
||||
|
||||
|
||||
if response.status_code != 200:
|
||||
raise HTTPException(
|
||||
status_code=response.status_code,
|
||||
|
|
@ -144,9 +143,12 @@ class OpenAIModerationGuardrail(OpenAIGuardrailBase, CustomGuardrail):
|
|||
)
|
||||
|
||||
from litellm.types.llms.openai import OpenAIModerationResponse
|
||||
|
||||
return OpenAIModerationResponse(**response.json())
|
||||
|
||||
def _check_moderation_result(self, moderation_response: "OpenAIModerationResponse") -> None:
|
||||
def _check_moderation_result(
|
||||
self, moderation_response: "OpenAIModerationResponse"
|
||||
) -> None:
|
||||
"""
|
||||
Check if the moderation response indicates harmful content and raise exception if needed.
|
||||
"""
|
||||
|
|
@ -168,10 +170,10 @@ class OpenAIModerationGuardrail(OpenAIGuardrailBase, CustomGuardrail):
|
|||
}
|
||||
|
||||
verbose_proxy_logger.warning(
|
||||
"OpenAI Moderation: Content flagged for violations: %s",
|
||||
violation_details
|
||||
"OpenAI Moderation: Content flagged for violations: %s",
|
||||
violation_details,
|
||||
)
|
||||
|
||||
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail={
|
||||
|
|
@ -180,6 +182,7 @@ class OpenAIModerationGuardrail(OpenAIGuardrailBase, CustomGuardrail):
|
|||
},
|
||||
)
|
||||
|
||||
@log_guardrail_information
|
||||
async def apply_guardrail(
|
||||
self,
|
||||
inputs: GenericGuardrailAPIInputs,
|
||||
|
|
@ -189,51 +192,50 @@ class OpenAIModerationGuardrail(OpenAIGuardrailBase, CustomGuardrail):
|
|||
) -> GenericGuardrailAPIInputs:
|
||||
"""
|
||||
Apply OpenAI moderation guardrail using the unified guardrail interface.
|
||||
|
||||
|
||||
This method is called by the UnifiedLLMGuardrails system for all endpoint types
|
||||
(chat completions, embeddings, responses API, etc.).
|
||||
|
||||
|
||||
Args:
|
||||
inputs: GenericGuardrailAPIInputs containing texts and/or structured_messages
|
||||
request_data: The original request data
|
||||
input_type: Whether this is a "request" (pre-call) or "response" (post-call)
|
||||
logging_obj: Optional logging object
|
||||
|
||||
|
||||
Returns:
|
||||
The inputs unchanged (moderation doesn't modify content, only blocks)
|
||||
|
||||
|
||||
Raises:
|
||||
HTTPException: If content violates moderation policy
|
||||
"""
|
||||
# Extract text to moderate from inputs
|
||||
text_to_moderate: Optional[str] = None
|
||||
|
||||
|
||||
# Prefer structured_messages if available (has role context)
|
||||
if structured_messages := inputs.get("structured_messages"):
|
||||
text_to_moderate = self.get_user_prompt(structured_messages)
|
||||
|
||||
|
||||
# Fall back to texts
|
||||
if not text_to_moderate:
|
||||
if texts := inputs.get("texts"):
|
||||
# Join all texts for moderation
|
||||
text_to_moderate = "\n".join(texts)
|
||||
|
||||
|
||||
if not text_to_moderate:
|
||||
verbose_proxy_logger.debug(
|
||||
"OpenAI Moderation: No text content to moderate in inputs"
|
||||
)
|
||||
return inputs
|
||||
|
||||
|
||||
# Make moderation request
|
||||
moderation_response = await self.async_make_request(input_text=text_to_moderate)
|
||||
|
||||
|
||||
# Check if content is flagged and raise exception if needed
|
||||
self._check_moderation_result(moderation_response)
|
||||
|
||||
|
||||
# Moderation doesn't modify content, just blocks - return inputs unchanged
|
||||
return inputs
|
||||
|
||||
|
||||
@log_guardrail_information
|
||||
async def async_post_call_streaming_iterator_hook(
|
||||
self,
|
||||
|
|
@ -252,9 +254,7 @@ class OpenAIModerationGuardrail(OpenAIGuardrailBase, CustomGuardrail):
|
|||
from litellm.main import stream_chunk_builder
|
||||
from litellm.types.utils import TextCompletionResponse
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
"OpenAI Moderation: Running streaming response scan"
|
||||
)
|
||||
verbose_proxy_logger.debug("OpenAI Moderation: Running streaming response scan")
|
||||
|
||||
# Collect all chunks to process them together
|
||||
all_chunks: List["ModelResponseStream"] = []
|
||||
|
|
@ -269,7 +269,7 @@ class OpenAIModerationGuardrail(OpenAIGuardrailBase, CustomGuardrail):
|
|||
)
|
||||
|
||||
if isinstance(assembled_model_response, (type(None), TextCompletionResponse)):
|
||||
# If we can't assemble a ModelResponse or it's a text completion,
|
||||
# If we can't assemble a ModelResponse or it's a text completion,
|
||||
# just yield the original chunks without moderation
|
||||
verbose_proxy_logger.warning(
|
||||
"OpenAI Moderation: Could not assemble ModelResponse from chunks, skipping moderation"
|
||||
|
|
@ -284,19 +284,17 @@ class OpenAIModerationGuardrail(OpenAIGuardrailBase, CustomGuardrail):
|
|||
verbose_proxy_logger.debug(
|
||||
f"OpenAI Moderation: Streaming response text: {response_text[:100]}..." # Log first 100 chars
|
||||
)
|
||||
|
||||
|
||||
# Make moderation request - this will raise HTTPException if content is flagged
|
||||
moderation_response = await self.async_make_request(
|
||||
input_text=response_text,
|
||||
)
|
||||
|
||||
|
||||
# Check if content is flagged and raise exception if needed
|
||||
self._check_moderation_result(moderation_response)
|
||||
|
||||
# If we reach here, content passed moderation - yield the original chunks
|
||||
mock_response = MockResponseIterator(
|
||||
model_response=assembled_model_response
|
||||
)
|
||||
mock_response = MockResponseIterator(model_response=assembled_model_response)
|
||||
|
||||
# Return the reconstructed stream
|
||||
async for chunk in mock_response:
|
||||
|
|
@ -306,34 +304,34 @@ class OpenAIModerationGuardrail(OpenAIGuardrailBase, CustomGuardrail):
|
|||
"""
|
||||
Extract text content from the model response for moderation.
|
||||
"""
|
||||
if not hasattr(response, 'choices') or not response.choices:
|
||||
if not hasattr(response, "choices") or not response.choices:
|
||||
return None
|
||||
|
||||
response_texts = []
|
||||
for choice in response.choices:
|
||||
try:
|
||||
# Try to get content from message (chat completion)
|
||||
message = getattr(choice, 'message', None)
|
||||
message = getattr(choice, "message", None)
|
||||
if message:
|
||||
content = getattr(message, 'content', None)
|
||||
content = getattr(message, "content", None)
|
||||
if content and isinstance(content, str):
|
||||
response_texts.append(content)
|
||||
continue
|
||||
|
||||
|
||||
# Try to get text (text completion)
|
||||
text = getattr(choice, 'text', None)
|
||||
text = getattr(choice, "text", None)
|
||||
if text and isinstance(text, str):
|
||||
response_texts.append(text)
|
||||
continue
|
||||
|
||||
|
||||
# Try to get content from delta (streaming)
|
||||
delta = getattr(choice, 'delta', None)
|
||||
delta = getattr(choice, "delta", None)
|
||||
if delta:
|
||||
content = getattr(delta, 'content', None)
|
||||
content = getattr(delta, "content", None)
|
||||
if content and isinstance(content, str):
|
||||
response_texts.append(content)
|
||||
continue
|
||||
|
||||
|
||||
except (AttributeError, TypeError):
|
||||
# Skip choices that don't have expected attributes
|
||||
continue
|
||||
|
|
|
|||
|
|
@ -9,10 +9,10 @@
|
|||
|
||||
|
||||
import asyncio
|
||||
import threading
|
||||
import json
|
||||
from datetime import datetime
|
||||
import threading
|
||||
from contextlib import asynccontextmanager
|
||||
from datetime import datetime
|
||||
from typing import (
|
||||
TYPE_CHECKING,
|
||||
Any,
|
||||
|
|
@ -38,8 +38,11 @@ if TYPE_CHECKING:
|
|||
|
||||
from litellm._uuid import uuid
|
||||
from litellm.caching.caching import DualCache
|
||||
from litellm.exceptions import BlockedPiiEntityError
|
||||
from litellm.integrations.custom_guardrail import CustomGuardrail
|
||||
from litellm.exceptions import BlockedPiiEntityError, GuardrailRaisedException
|
||||
from litellm.integrations.custom_guardrail import (
|
||||
CustomGuardrail,
|
||||
log_guardrail_information,
|
||||
)
|
||||
from litellm.proxy._types import UserAPIKeyAuth
|
||||
from litellm.types.guardrails import (
|
||||
GuardrailEventHooks,
|
||||
|
|
@ -229,6 +232,14 @@ class _OPTIONAL_PresidioPIIMasking(CustomGuardrail):
|
|||
"""Cleanup: we try to close, but doing async cleanup in __del__ is risky."""
|
||||
pass
|
||||
|
||||
def _has_block_action(self) -> bool:
|
||||
"""Return True if pii_entities_config has any BLOCK action (fail-closed on analyzer errors)."""
|
||||
if not self.pii_entities_config:
|
||||
return False
|
||||
return any(
|
||||
action == PiiAction.BLOCK for action in self.pii_entities_config.values()
|
||||
)
|
||||
|
||||
def _get_presidio_analyze_request_payload(
|
||||
self,
|
||||
text: str,
|
||||
|
|
@ -313,13 +324,30 @@ class _OPTIONAL_PresidioPIIMasking(CustomGuardrail):
|
|||
|
||||
# Handle error responses from Presidio (e.g., {'error': 'No text provided'})
|
||||
# Presidio may return a dict instead of a list when errors occur
|
||||
def _fail_on_invalid_response(
|
||||
reason: str,
|
||||
) -> List[PresidioAnalyzeResponseItem]:
|
||||
should_fail_closed = (
|
||||
bool(self.pii_entities_config)
|
||||
or self.output_parse_pii
|
||||
or self.apply_to_output
|
||||
)
|
||||
if should_fail_closed:
|
||||
raise GuardrailRaisedException(
|
||||
guardrail_name=self.guardrail_name,
|
||||
message=f"Presidio analyzer returned invalid response; cannot verify PII when PII protection is configured: {reason}",
|
||||
should_wrap_with_default_message=False,
|
||||
)
|
||||
verbose_proxy_logger.warning(
|
||||
"Presidio analyzer %s, returning empty list", reason
|
||||
)
|
||||
return []
|
||||
|
||||
if isinstance(analyze_results, dict):
|
||||
if "error" in analyze_results:
|
||||
verbose_proxy_logger.warning(
|
||||
"Presidio analyzer returned error: %s, returning empty list",
|
||||
analyze_results.get("error"),
|
||||
return _fail_on_invalid_response(
|
||||
f"error: {analyze_results.get('error')}"
|
||||
)
|
||||
return []
|
||||
# If it's a dict but not an error, try to process it as a single item
|
||||
verbose_proxy_logger.debug(
|
||||
"Presidio returned dict (not list), attempting to process as single item"
|
||||
|
|
@ -327,23 +355,33 @@ class _OPTIONAL_PresidioPIIMasking(CustomGuardrail):
|
|||
try:
|
||||
return [PresidioAnalyzeResponseItem(**analyze_results)]
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.warning(
|
||||
"Failed to parse Presidio dict response: %s, returning empty list",
|
||||
e,
|
||||
return _fail_on_invalid_response(
|
||||
f"failed to parse dict response: {e}"
|
||||
)
|
||||
return []
|
||||
|
||||
# Handle unexpected types (str, None, etc.) - e.g. from malformed/error
|
||||
if not isinstance(analyze_results, list):
|
||||
return _fail_on_invalid_response(
|
||||
f"unexpected type {type(analyze_results).__name__} (expected list or dict), response: {str(analyze_results)[:200]}"
|
||||
)
|
||||
|
||||
# Normal case: list of results
|
||||
final_results = []
|
||||
for item in analyze_results:
|
||||
if not isinstance(item, dict):
|
||||
verbose_proxy_logger.warning(
|
||||
"Skipping invalid Presidio result item (expected dict, got %s): %s",
|
||||
type(item).__name__,
|
||||
str(item)[:100],
|
||||
)
|
||||
continue
|
||||
try:
|
||||
final_results.append(PresidioAnalyzeResponseItem(**item))
|
||||
except TypeError as te:
|
||||
# Handle case where item is not a dict (shouldn't happen, but be defensive)
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.warning(
|
||||
"Skipping invalid Presidio result item: %s (error: %s)",
|
||||
"Failed to parse Presidio result item: %s (error: %s)",
|
||||
item,
|
||||
te,
|
||||
e,
|
||||
)
|
||||
continue
|
||||
return final_results
|
||||
|
|
@ -568,9 +606,9 @@ class _OPTIONAL_PresidioPIIMasking(CustomGuardrail):
|
|||
if messages is None:
|
||||
return data
|
||||
tasks = []
|
||||
task_mappings: List[
|
||||
Tuple[int, Optional[int]]
|
||||
] = [] # Track (message_index, content_index) for each task
|
||||
task_mappings: List[Tuple[int, Optional[int]]] = (
|
||||
[]
|
||||
) # Track (message_index, content_index) for each task
|
||||
|
||||
for msg_idx, m in enumerate(messages):
|
||||
content = m.get("content", None)
|
||||
|
|
@ -671,9 +709,9 @@ class _OPTIONAL_PresidioPIIMasking(CustomGuardrail):
|
|||
): # /chat/completions requests
|
||||
messages: Optional[List] = kwargs.get("messages", None)
|
||||
tasks = []
|
||||
task_mappings: List[
|
||||
Tuple[int, Optional[int]]
|
||||
] = [] # Track (message_index, content_index) for each task
|
||||
task_mappings: List[Tuple[int, Optional[int]]] = (
|
||||
[]
|
||||
) # Track (message_index, content_index) for each task
|
||||
|
||||
if messages is None:
|
||||
return kwargs, result
|
||||
|
|
@ -792,11 +830,11 @@ class _OPTIONAL_PresidioPIIMasking(CustomGuardrail):
|
|||
# Type narrowing: StreamingChoices doesn't have .message attribute
|
||||
if not hasattr(choice, "message"):
|
||||
continue
|
||||
content = getattr(choice.message, "content", None)
|
||||
content = getattr(choice.message, "content", None) # type: ignore
|
||||
if content is None:
|
||||
continue
|
||||
if isinstance(content, str):
|
||||
choice.message.content = await self.check_pii(
|
||||
choice.message.content = await self.check_pii( # type: ignore
|
||||
text=content,
|
||||
output_parse_pii=False,
|
||||
presidio_config=presidio_config,
|
||||
|
|
@ -989,6 +1027,7 @@ class _OPTIONAL_PresidioPIIMasking(CustomGuardrail):
|
|||
except Exception:
|
||||
pass
|
||||
|
||||
@log_guardrail_information
|
||||
async def apply_guardrail(
|
||||
self,
|
||||
inputs: "GenericGuardrailAPIInputs",
|
||||
|
|
|
|||
|
|
@ -6,7 +6,10 @@ from typing import TYPE_CHECKING, Any, List, Literal, Optional, Type
|
|||
from fastapi import HTTPException
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.integrations.custom_guardrail import CustomGuardrail
|
||||
from litellm.integrations.custom_guardrail import (
|
||||
CustomGuardrail,
|
||||
log_guardrail_information,
|
||||
)
|
||||
from litellm.llms.custom_httpx.http_handler import (
|
||||
get_async_httpx_client,
|
||||
httpxSpecialProvider,
|
||||
|
|
@ -67,6 +70,7 @@ class PromptSecurityGuardrail(CustomGuardrail):
|
|||
|
||||
super().__init__(**kwargs)
|
||||
|
||||
@log_guardrail_information
|
||||
async def apply_guardrail(
|
||||
self,
|
||||
inputs: GenericGuardrailAPIInputs,
|
||||
|
|
|
|||
|
|
@ -12,10 +12,11 @@ from typing import Any, Dict, List, Literal, Optional, Type
|
|||
from fastapi import HTTPException
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.integrations.custom_guardrail import CustomGuardrail
|
||||
from litellm.litellm_core_utils.litellm_logging import (
|
||||
Logging as LiteLLMLoggingObj,
|
||||
from litellm.integrations.custom_guardrail import (
|
||||
CustomGuardrail,
|
||||
log_guardrail_information,
|
||||
)
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj
|
||||
from litellm.llms.custom_httpx.http_handler import (
|
||||
get_async_httpx_client,
|
||||
httpxSpecialProvider,
|
||||
|
|
@ -343,9 +344,7 @@ class QualifireGuardrail(CustomGuardrail):
|
|||
)
|
||||
url = f"{self.qualifire_api_base}/api/evaluation/evaluate"
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
f"Qualifire Guardrail: Making request to {url}"
|
||||
)
|
||||
verbose_proxy_logger.debug(f"Qualifire Guardrail: Making request to {url}")
|
||||
|
||||
# Make the API request
|
||||
response = await self.async_handler.post(
|
||||
|
|
@ -393,6 +392,7 @@ class QualifireGuardrail(CustomGuardrail):
|
|||
verbose_proxy_logger.exception(f"Qualifire Guardrail error: {e}")
|
||||
raise
|
||||
|
||||
@log_guardrail_information
|
||||
async def apply_guardrail(
|
||||
self,
|
||||
inputs: GenericGuardrailAPIInputs,
|
||||
|
|
|
|||
|
|
@ -9,7 +9,10 @@ from typing import TYPE_CHECKING, Literal, Optional
|
|||
from fastapi import HTTPException
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.integrations.custom_guardrail import CustomGuardrail
|
||||
from litellm.integrations.custom_guardrail import (
|
||||
CustomGuardrail,
|
||||
log_guardrail_information,
|
||||
)
|
||||
from litellm.llms.custom_httpx.http_handler import (
|
||||
get_async_httpx_client,
|
||||
httpxSpecialProvider,
|
||||
|
|
@ -70,6 +73,7 @@ class ZscalerAIGuard(CustomGuardrail):
|
|||
return str(value).strip()
|
||||
return "N/A"
|
||||
|
||||
@log_guardrail_information
|
||||
async def apply_guardrail(
|
||||
self,
|
||||
inputs: "GenericGuardrailAPIInputs",
|
||||
|
|
@ -92,7 +96,7 @@ class ZscalerAIGuard(CustomGuardrail):
|
|||
Raises:
|
||||
Exception: If content is blocked by Zscaler AI Guard
|
||||
"""
|
||||
|
||||
|
||||
texts = inputs.get("texts", [])
|
||||
try:
|
||||
verbose_proxy_logger.debug(f"ZscalerAIGuard: Checking {len(texts)} text(s)")
|
||||
|
|
@ -102,8 +106,8 @@ class ZscalerAIGuard(CustomGuardrail):
|
|||
team_metadata = metadata.get("team_metadata", {}) or {}
|
||||
|
||||
# Precedence for policy_id:
|
||||
# 1. metadata.zguard_policy_id # request level
|
||||
# 2. user_api_key_metadata.zguard_policy_id # Key level
|
||||
# 1. metadata.zguard_policy_id # request level
|
||||
# 2. user_api_key_metadata.zguard_policy_id # Key level
|
||||
# 3. team_metadata.zguard_policy_id # Team level
|
||||
# 4. self.policy_id (from environment) # Global
|
||||
policy_id = (
|
||||
|
|
@ -154,9 +158,7 @@ class ZscalerAIGuard(CustomGuardrail):
|
|||
zscaler_ai_guard_result
|
||||
and zscaler_ai_guard_result.get("action") == "BLOCK"
|
||||
):
|
||||
blocking_info = zscaler_ai_guard_result.get(
|
||||
"zscaler_ai_guard_response"
|
||||
)
|
||||
blocking_info = zscaler_ai_guard_result.get("zscaler_ai_guard_response")
|
||||
error_message = f"Content blocked by Zscaler AI Guard: {self.extract_blocking_info(blocking_info)}"
|
||||
raise Exception(error_message)
|
||||
except Exception as e:
|
||||
|
|
|
|||
|
|
@ -17,7 +17,7 @@ Quick summary:
|
|||
- async_log_success_event() fires on GET /v1/batches/{id} (batch completion)
|
||||
"""
|
||||
|
||||
from typing import TYPE_CHECKING, Any, Dict, List, Literal, Union
|
||||
from typing import TYPE_CHECKING, Any, Dict, List, Literal, Optional, Union
|
||||
|
||||
from fastapi import HTTPException
|
||||
from pydantic import BaseModel
|
||||
|
|
@ -241,6 +241,7 @@ class _PROXY_BatchRateLimiter(CustomLogger):
|
|||
self,
|
||||
file_id: str,
|
||||
custom_llm_provider: Literal["openai", "azure", "vertex_ai"] = "openai",
|
||||
user_api_key_dict: Optional[UserAPIKeyAuth] = None,
|
||||
) -> BatchFileUsage:
|
||||
"""
|
||||
Count number of requests and tokens in a batch input file.
|
||||
|
|
@ -248,6 +249,7 @@ class _PROXY_BatchRateLimiter(CustomLogger):
|
|||
Args:
|
||||
file_id: The file ID to read
|
||||
custom_llm_provider: The custom LLM provider to use for token encoding
|
||||
user_api_key_dict: User authentication information for file access (required for managed files)
|
||||
|
||||
Returns:
|
||||
BatchFileUsage with total_tokens and request_count
|
||||
|
|
@ -257,6 +259,7 @@ class _PROXY_BatchRateLimiter(CustomLogger):
|
|||
file_content = await litellm.afile_content(
|
||||
file_id=file_id,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
)
|
||||
|
||||
file_content_as_dict = _get_file_content_as_dictionary(
|
||||
|
|
@ -336,6 +339,7 @@ class _PROXY_BatchRateLimiter(CustomLogger):
|
|||
batch_usage = await self.count_input_file_usage(
|
||||
file_id=input_file_id,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
)
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
|
|
|
|||
|
|
@ -262,6 +262,67 @@ if MCP_AVAILABLE:
|
|||
) -> List[LiteLLM_MCPServerTable]:
|
||||
return [_redact_mcp_credentials(server) for server in mcp_servers]
|
||||
|
||||
def _is_restricted_virtual_key_request(user_api_key_dict: UserAPIKeyAuth) -> bool:
|
||||
"""Best-effort detection for route-restricted virtual keys.
|
||||
|
||||
We treat a requestor as a "restricted" virtual key if `allowed_routes`
|
||||
is a non-empty list. This matches the auth gate that blocks routes with
|
||||
the error: "Virtual key is not allowed to call this route...".
|
||||
"""
|
||||
|
||||
allowed_routes = getattr(user_api_key_dict, "allowed_routes", None)
|
||||
return isinstance(allowed_routes, list) and len(allowed_routes) > 0
|
||||
|
||||
def _sanitize_mcp_server_for_virtual_key(
|
||||
mcp_server: LiteLLM_MCPServerTable,
|
||||
) -> LiteLLM_MCPServerTable:
|
||||
"""Return a minimally sufficient MCP server view for virtual keys.
|
||||
|
||||
Security model:
|
||||
- Virtual keys should be able to *discover* accessible servers.
|
||||
- They should NOT receive sensitive configuration details like upstream
|
||||
URLs, env vars, headers, commands/args, access-group names, or
|
||||
credentials.
|
||||
"""
|
||||
|
||||
sanitized = _redact_mcp_credentials(mcp_server)
|
||||
|
||||
# Remove potentially sensitive config + identity fields.
|
||||
sanitized.url = None
|
||||
sanitized.static_headers = None
|
||||
sanitized.env = {}
|
||||
sanitized.command = None
|
||||
sanitized.args = []
|
||||
sanitized.extra_headers = []
|
||||
sanitized.allowed_tools = []
|
||||
sanitized.mcp_access_groups = []
|
||||
sanitized.teams = []
|
||||
|
||||
sanitized.authorization_url = None
|
||||
sanitized.token_url = None
|
||||
sanitized.registration_url = None
|
||||
|
||||
sanitized.health_check_error = None
|
||||
sanitized.last_health_check = None
|
||||
|
||||
sanitized.created_by = None
|
||||
sanitized.updated_by = None
|
||||
sanitized.created_at = None
|
||||
sanitized.updated_at = None
|
||||
|
||||
# `mcp_info` is arbitrary metadata; keep only an explicit safe subset.
|
||||
is_public = False
|
||||
if isinstance(sanitized.mcp_info, dict):
|
||||
is_public = bool(sanitized.mcp_info.get("is_public"))
|
||||
sanitized.mcp_info = {"is_public": True} if is_public else None
|
||||
|
||||
return sanitized
|
||||
|
||||
def _sanitize_mcp_server_list_for_virtual_key(
|
||||
mcp_servers: Iterable[LiteLLM_MCPServerTable],
|
||||
) -> List[LiteLLM_MCPServerTable]:
|
||||
return [_sanitize_mcp_server_for_virtual_key(server) for server in mcp_servers]
|
||||
|
||||
def _inherit_credentials_from_existing_server(
|
||||
payload: NewMCPServerRequest,
|
||||
) -> NewMCPServerRequest:
|
||||
|
|
@ -504,8 +565,11 @@ if MCP_AVAILABLE:
|
|||
"""
|
||||
|
||||
user_mcp_management_mode = _get_user_mcp_management_mode()
|
||||
is_restricted_virtual_key = _is_restricted_virtual_key_request(
|
||||
user_api_key_dict
|
||||
)
|
||||
|
||||
if user_mcp_management_mode == "view_all":
|
||||
if user_mcp_management_mode == "view_all" and not is_restricted_virtual_key:
|
||||
servers = await global_mcp_server_manager.get_all_mcp_servers_unfiltered()
|
||||
redacted_mcp_servers = _redact_mcp_credentials_list(servers)
|
||||
else:
|
||||
|
|
@ -531,6 +595,11 @@ if MCP_AVAILABLE:
|
|||
if server.mcp_info is None:
|
||||
server.mcp_info = {}
|
||||
server.mcp_info["is_public"] = True
|
||||
|
||||
# Virtual keys only get a sanitized discovery view.
|
||||
if is_restricted_virtual_key:
|
||||
return _sanitize_mcp_server_list_for_virtual_key(redacted_mcp_servers)
|
||||
|
||||
return redacted_mcp_servers
|
||||
|
||||
@router.get(
|
||||
|
|
@ -625,6 +694,34 @@ if MCP_AVAILABLE:
|
|||
detail={"error": f"MCP Server with id {server_id} not found"},
|
||||
)
|
||||
|
||||
# Implement authz restriction from requested user
|
||||
is_admin_view = _user_has_admin_view(user_api_key_dict)
|
||||
is_restricted_virtual_key = _is_restricted_virtual_key_request(
|
||||
user_api_key_dict
|
||||
)
|
||||
|
||||
if not is_admin_view:
|
||||
# Perform authz check BEFORE any health check (avoid side-effects for
|
||||
# unauthorized callers).
|
||||
mcp_server_records = await get_all_mcp_servers_for_user(
|
||||
prisma_client, user_api_key_dict
|
||||
)
|
||||
exists = does_mcp_server_exist(mcp_server_records, server_id)
|
||||
|
||||
if not exists:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_403_FORBIDDEN,
|
||||
detail={
|
||||
"error": (
|
||||
f"User does not have permission to view mcp server with id {server_id}. "
|
||||
"You can only view mcp servers that you have access to."
|
||||
)
|
||||
},
|
||||
)
|
||||
|
||||
# At this point caller is authorized to view the server.
|
||||
await global_mcp_server_manager.add_server(mcp_server)
|
||||
|
||||
# Perform health check on the server using server manager
|
||||
try:
|
||||
health_result = await global_mcp_server_manager.health_check_server(
|
||||
|
|
@ -644,26 +741,10 @@ if MCP_AVAILABLE:
|
|||
mcp_server.last_health_check = datetime.now()
|
||||
mcp_server.health_check_error = str(e)
|
||||
|
||||
# Implement authz restriction from requested user
|
||||
if _user_has_admin_view(user_api_key_dict):
|
||||
return _redact_mcp_credentials(mcp_server)
|
||||
|
||||
# Perform authz check to filter the mcp servers user has access to
|
||||
mcp_server_records = await get_all_mcp_servers_for_user(
|
||||
prisma_client, user_api_key_dict
|
||||
)
|
||||
exists = does_mcp_server_exist(mcp_server_records, server_id)
|
||||
|
||||
if exists:
|
||||
await global_mcp_server_manager.add_server(mcp_server)
|
||||
return _redact_mcp_credentials(mcp_server)
|
||||
else:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_403_FORBIDDEN,
|
||||
detail={
|
||||
"error": f"User does not have permission to view mcp server with id {server_id}. You can only view mcp servers that you have access to."
|
||||
},
|
||||
)
|
||||
redacted = _redact_mcp_credentials(mcp_server)
|
||||
if is_restricted_virtual_key:
|
||||
return _sanitize_mcp_server_for_virtual_key(redacted)
|
||||
return redacted
|
||||
|
||||
@router.post(
|
||||
"/server",
|
||||
|
|
|
|||
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue