mirror of
https://github.com/BerriAI/litellm.git
synced 2026-10-08 03:08:45 +00:00
Merge remote-tracking branch 'origin' into litellm_endpoint_usage_breakdown
This commit is contained in:
 yuneng-jiang
commit
7da8d5fcd5
83 changed files with 3991 additions and 564 deletions
|
|
@ -1465,7 +1465,7 @@ jobs:
|
|||
- run:
|
||||
name: Run core tests
|
||||
command: |
|
||||
python -m pytest tests/test_litellm --ignore=tests/test_litellm/proxy --ignore=tests/test_litellm/llms --cov=litellm --cov-report=xml --junitxml=test-results/junit-core.xml --durations=10 -n 16 --maxfail=5 --timeout=300 -vv --log-cli-level=WARNING
|
||||
python -m pytest tests/test_litellm --ignore=tests/test_litellm/proxy --ignore=tests/test_litellm/llms --ignore=tests/test_litellm/integrations --ignore=tests/test_litellm/litellm_core_utils --cov=litellm --cov-report=xml --junitxml=test-results/junit-core.xml --durations=10 -n 16 --maxfail=5 --timeout=300 -vv --log-cli-level=WARNING
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
|
|
@ -1479,6 +1479,60 @@ jobs:
|
|||
paths:
|
||||
- litellm_core_tests_coverage.xml
|
||||
- litellm_core_tests_coverage
|
||||
litellm_mapped_tests_litellm_core_utils:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
resource_class: xlarge
|
||||
steps:
|
||||
- setup_litellm_test_deps
|
||||
- run:
|
||||
name: Run litellm_core_utils tests
|
||||
command: |
|
||||
python -m pytest tests/test_litellm/litellm_core_utils --cov=litellm --cov-report=xml --junitxml=test-results/junit-litellm-core-utils.xml --durations=10 -n 16 --maxfail=5 --timeout=300 -vv --log-cli-level=WARNING
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml litellm_core_utils_tests_coverage.xml
|
||||
mv .coverage litellm_core_utils_tests_coverage
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm_core_utils_tests_coverage.xml
|
||||
- litellm_core_utils_tests_coverage
|
||||
litellm_mapped_tests_integrations:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
resource_class: xlarge
|
||||
steps:
|
||||
- setup_litellm_test_deps
|
||||
- run:
|
||||
name: Run integrations tests
|
||||
command: |
|
||||
python -m pytest tests/test_litellm/integrations --cov=litellm --cov-report=xml --junitxml=test-results/junit-integrations.xml --durations=10 -n 16 --maxfail=5 --timeout=300 -vv --log-cli-level=WARNING
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml litellm_integrations_tests_coverage.xml
|
||||
mv .coverage litellm_integrations_tests_coverage
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm_integrations_tests_coverage.xml
|
||||
- litellm_integrations_tests_coverage
|
||||
litellm_mapped_enterprise_tests:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
|
|
@ -1960,6 +2014,7 @@ jobs:
|
|||
- run: ruff check ./litellm
|
||||
# - run: python ./tests/documentation_tests/test_general_setting_keys.py
|
||||
- run: python ./tests/code_coverage_tests/check_licenses.py
|
||||
- run: python ./tests/code_coverage_tests/check_provider_folders_documented.py
|
||||
- run: python ./tests/code_coverage_tests/router_code_coverage.py
|
||||
- run: python ./tests/code_coverage_tests/test_chat_completion_imports.py
|
||||
- run: python ./tests/code_coverage_tests/info_log_check.py
|
||||
|
|
@ -3871,6 +3926,18 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_mapped_tests_integrations:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_mapped_tests_litellm_core_utils:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- batches_testing:
|
||||
filters:
|
||||
branches:
|
||||
|
|
@ -3919,6 +3986,8 @@ workflows:
|
|||
- litellm_mapped_tests_proxy
|
||||
- litellm_mapped_tests_llms
|
||||
- litellm_mapped_tests_core
|
||||
- litellm_mapped_tests_integrations
|
||||
- litellm_mapped_tests_litellm_core_utils
|
||||
- litellm_mapped_enterprise_tests
|
||||
- batches_testing
|
||||
- litellm_utils_testing
|
||||
|
|
@ -3990,6 +4059,8 @@ workflows:
|
|||
- litellm_mapped_tests_proxy
|
||||
- litellm_mapped_tests_llms
|
||||
- litellm_mapped_tests_core
|
||||
- litellm_mapped_tests_integrations
|
||||
- litellm_mapped_tests_litellm_core_utils
|
||||
- litellm_mapped_enterprise_tests
|
||||
- batches_testing
|
||||
- litellm_utils_testing
|
||||
|
|
|
|||
1
.github/ISSUE_TEMPLATE/bug_report.yml
vendored
1
.github/ISSUE_TEMPLATE/bug_report.yml
vendored
|
|
@ -27,6 +27,7 @@ body:
|
|||
attributes:
|
||||
label: What part of LiteLLM is this about?
|
||||
options:
|
||||
- ''
|
||||
- "SDK (litellm Python package)"
|
||||
- "Proxy"
|
||||
- "UI Dashboard"
|
||||
|
|
|
|||
1
.github/ISSUE_TEMPLATE/feature_request.yml
vendored
1
.github/ISSUE_TEMPLATE/feature_request.yml
vendored
|
|
@ -27,6 +27,7 @@ body:
|
|||
attributes:
|
||||
label: What part of LiteLLM is this about?
|
||||
options:
|
||||
- ''
|
||||
- "SDK (litellm Python package)"
|
||||
- "Proxy"
|
||||
- "UI Dashboard"
|
||||
|
|
|
|||
8
.github/workflows/label-component.yml
vendored
8
.github/workflows/label-component.yml
vendored
|
|
@ -12,7 +12,7 @@ jobs:
|
|||
issues: write
|
||||
steps:
|
||||
- name: Add SDK label
|
||||
if: contains(github.event.issue.body, 'SDK (litellm Python package)')
|
||||
if: contains(github.event.issue.body, 'What part of LiteLLM is this about?\n\nSDK (litellm Python package)')
|
||||
uses: actions/github-script@v7
|
||||
with:
|
||||
github-token: ${{ secrets.GITHUB_TOKEN }}
|
||||
|
|
@ -45,7 +45,7 @@ jobs:
|
|||
});
|
||||
|
||||
- name: Add Proxy label
|
||||
if: contains(github.event.issue.body, 'Proxy')
|
||||
if: contains(github.event.issue.body, 'What part of LiteLLM is this about?\n\nProxy')
|
||||
uses: actions/github-script@v7
|
||||
with:
|
||||
github-token: ${{ secrets.GITHUB_TOKEN }}
|
||||
|
|
@ -78,7 +78,7 @@ jobs:
|
|||
});
|
||||
|
||||
- name: Add UI Dashboard label
|
||||
if: contains(github.event.issue.body, 'UI Dashboard')
|
||||
if: contains(github.event.issue.body, 'What part of LiteLLM is this about?\n\nUI Dashboard')
|
||||
uses: actions/github-script@v7
|
||||
with:
|
||||
github-token: ${{ secrets.GITHUB_TOKEN }}
|
||||
|
|
@ -111,7 +111,7 @@ jobs:
|
|||
});
|
||||
|
||||
- name: Add Docs label
|
||||
if: contains(github.event.issue.body, 'Docs')
|
||||
if: contains(github.event.issue.body, 'What part of LiteLLM is this about?\n\nDocs')
|
||||
uses: actions/github-script@v7
|
||||
with:
|
||||
github-token: ${{ secrets.GITHUB_TOKEN }}
|
||||
|
|
|
|||
|
|
@ -34,47 +34,47 @@ install_ggshield() {
|
|||
echo "ggshield installed successfully"
|
||||
}
|
||||
|
||||
# Function to run secret detection scans
|
||||
run_secret_detection() {
|
||||
echo "Running secret detection scans..."
|
||||
# # Function to run secret detection scans
|
||||
# run_secret_detection() {
|
||||
# echo "Running secret detection scans..."
|
||||
|
||||
if ! command -v ggshield &> /dev/null; then
|
||||
install_ggshield
|
||||
fi
|
||||
# if ! command -v ggshield &> /dev/null; then
|
||||
# install_ggshield
|
||||
# fi
|
||||
|
||||
# Check if GITGUARDIAN_API_KEY is set (required for CI/CD)
|
||||
if [ -z "$GITGUARDIAN_API_KEY" ]; then
|
||||
echo "Warning: GITGUARDIAN_API_KEY environment variable is not set."
|
||||
echo "ggshield requires a GitGuardian API key to scan for secrets."
|
||||
echo "Please set GITGUARDIAN_API_KEY in your CI/CD environment variables."
|
||||
exit 1
|
||||
fi
|
||||
# # Check if GITGUARDIAN_API_KEY is set (required for CI/CD)
|
||||
# if [ -z "$GITGUARDIAN_API_KEY" ]; then
|
||||
# echo "Warning: GITGUARDIAN_API_KEY environment variable is not set."
|
||||
# echo "ggshield requires a GitGuardian API key to scan for secrets."
|
||||
# echo "Please set GITGUARDIAN_API_KEY in your CI/CD environment variables."
|
||||
# exit 1
|
||||
# fi
|
||||
|
||||
echo "Scanning codebase for secrets..."
|
||||
echo "Note: Large codebases may take several minutes due to API rate limits (50 requests/minute on free plan)"
|
||||
echo "ggshield will automatically handle rate limits and retry as needed."
|
||||
echo "Binary files, cache files, and build artifacts are excluded via .gitguardian.yaml"
|
||||
# echo "Scanning codebase for secrets..."
|
||||
# echo "Note: Large codebases may take several minutes due to API rate limits (50 requests/minute on free plan)"
|
||||
# echo "ggshield will automatically handle rate limits and retry as needed."
|
||||
# echo "Binary files, cache files, and build artifacts are excluded via .gitguardian.yaml"
|
||||
|
||||
# Use --recursive for directory scanning and auto-confirm if prompted
|
||||
# .gitguardian.yaml will automatically exclude binary files, wheel files, etc.
|
||||
# GITGUARDIAN_API_KEY environment variable will be used for authentication
|
||||
echo y | ggshield secret scan path . --recursive || {
|
||||
echo ""
|
||||
echo "=========================================="
|
||||
echo "ERROR: Secret Detection Failed"
|
||||
echo "=========================================="
|
||||
echo "ggshield has detected secrets in the codebase."
|
||||
echo "Please review discovered secrets above, revoke any actively used secrets"
|
||||
echo "from underlying systems and make changes to inject secrets dynamically at runtime."
|
||||
echo ""
|
||||
echo "For more information, see: https://docs.gitguardian.com/secrets-detection/"
|
||||
echo "=========================================="
|
||||
echo ""
|
||||
exit 1
|
||||
}
|
||||
# # Use --recursive for directory scanning and auto-confirm if prompted
|
||||
# # .gitguardian.yaml will automatically exclude binary files, wheel files, etc.
|
||||
# # GITGUARDIAN_API_KEY environment variable will be used for authentication
|
||||
# echo y | ggshield secret scan path . --recursive || {
|
||||
# echo ""
|
||||
# echo "=========================================="
|
||||
# echo "ERROR: Secret Detection Failed"
|
||||
# echo "=========================================="
|
||||
# echo "ggshield has detected secrets in the codebase."
|
||||
# echo "Please review discovered secrets above, revoke any actively used secrets"
|
||||
# echo "from underlying systems and make changes to inject secrets dynamically at runtime."
|
||||
# echo ""
|
||||
# echo "For more information, see: https://docs.gitguardian.com/secrets-detection/"
|
||||
# echo "=========================================="
|
||||
# echo ""
|
||||
# exit 1
|
||||
# }
|
||||
|
||||
echo "Secret detection scans completed successfully"
|
||||
}
|
||||
# echo "Secret detection scans completed successfully"
|
||||
# }
|
||||
|
||||
# Function to run Trivy scans
|
||||
run_trivy_scans() {
|
||||
|
|
@ -209,8 +209,8 @@ main() {
|
|||
install_trivy
|
||||
install_grype
|
||||
|
||||
echo "Running secret detection scans..."
|
||||
run_secret_detection
|
||||
# echo "Running secret detection scans..."
|
||||
# run_secret_detection
|
||||
|
||||
echo "Running filesystem vulnerability scans..."
|
||||
run_trivy_scans
|
||||
|
|
|
|||
|
|
@ -21,6 +21,7 @@ Looking for how to use Code Interpreter? See the [Code Interpreter Guide](/docs/
|
|||
|
||||
| Endpoint | Method | Description |
|
||||
|----------|--------|-------------|
|
||||
| `/v1/containers/{container_id}/files` | POST | Upload file to container |
|
||||
| `/v1/containers/{container_id}/files` | GET | List files in container |
|
||||
| `/v1/containers/{container_id}/files/{file_id}` | GET | Get file metadata |
|
||||
| `/v1/containers/{container_id}/files/{file_id}/content` | GET | Download file content |
|
||||
|
|
@ -28,6 +29,45 @@ Looking for how to use Code Interpreter? See the [Code Interpreter Guide](/docs/
|
|||
|
||||
## LiteLLM Python SDK
|
||||
|
||||
### Upload Container File
|
||||
|
||||
Upload files directly to a container session. This is useful when `/chat/completions` or `/responses` sends files to the container but the input file type is limited to PDF. This endpoint lets you work with other file types like CSV, Excel, Python scripts, etc.
|
||||
|
||||
```python showLineNumbers title="upload_container_file.py"
|
||||
from litellm import upload_container_file
|
||||
|
||||
# Upload a CSV file
|
||||
file = upload_container_file(
|
||||
container_id="cntr_123...",
|
||||
file=("data.csv", open("data.csv", "rb").read(), "text/csv"),
|
||||
custom_llm_provider="openai"
|
||||
)
|
||||
|
||||
print(f"Uploaded: {file.id}")
|
||||
print(f"Path: {file.path}")
|
||||
```
|
||||
|
||||
**Async:**
|
||||
|
||||
```python showLineNumbers title="aupload_container_file.py"
|
||||
from litellm import aupload_container_file
|
||||
|
||||
file = await aupload_container_file(
|
||||
container_id="cntr_123...",
|
||||
file=("script.py", b"print('hello world')", "text/x-python"),
|
||||
custom_llm_provider="openai"
|
||||
)
|
||||
```
|
||||
|
||||
**Supported file formats:**
|
||||
- CSV (`.csv`)
|
||||
- Excel (`.xlsx`)
|
||||
- Python scripts (`.py`)
|
||||
- JSON (`.json`)
|
||||
- Markdown (`.md`)
|
||||
- Text files (`.txt`)
|
||||
- And more...
|
||||
|
||||
### List Container Files
|
||||
|
||||
```python showLineNumbers title="list_container_files.py"
|
||||
|
|
@ -103,6 +143,40 @@ print(f"Deleted: {result.deleted}")
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
### Upload File
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="openai-sdk" label="OpenAI SDK">
|
||||
|
||||
```python showLineNumbers title="upload_file.py"
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
api_key="sk-1234",
|
||||
base_url="http://localhost:4000"
|
||||
)
|
||||
|
||||
file = client.containers.files.create(
|
||||
container_id="cntr_123...",
|
||||
file=open("data.csv", "rb")
|
||||
)
|
||||
|
||||
print(f"Uploaded: {file.id}")
|
||||
print(f"Path: {file.path}")
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="curl" label="curl">
|
||||
|
||||
```bash showLineNumbers title="upload_file.sh"
|
||||
curl "http://localhost:4000/v1/containers/cntr_123.../files" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-F file="@data.csv"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### List Files
|
||||
|
||||
<Tabs>
|
||||
|
|
@ -236,6 +310,13 @@ curl -X DELETE "http://localhost:4000/v1/containers/cntr_123.../files/cfile_456.
|
|||
|
||||
## Parameters
|
||||
|
||||
### Upload File
|
||||
|
||||
| Parameter | Type | Required | Description |
|
||||
|-----------|------|----------|-------------|
|
||||
| `container_id` | string | Yes | Container ID |
|
||||
| `file` | FileTypes | Yes | File to upload. Can be a tuple of (filename, content, content_type), file-like object, or bytes |
|
||||
|
||||
### List Files
|
||||
|
||||
| Parameter | Type | Required | Description |
|
||||
|
|
|
|||
|
|
@ -8,7 +8,7 @@ import TabItem from '@theme/TabItem';
|
|||
| Logging | ✅ | Works across all integrations |
|
||||
| Streaming | ✅ | |
|
||||
| Loadbalancing | ✅ | Between supported models |
|
||||
| Supported LLM providers | **All LiteLLM supported providers** | `openai`, `anthropic`, `bedrock`, `vertex_ai`, `gemini`, `azure`, `azure_ai` etc. |
|
||||
| Supported LLM providers | **All LiteLLM supported CHAT COMPLETION providers** | `openai`, `anthropic`, `bedrock`, `vertex_ai`, `gemini`, `azure`, `azure_ai` etc. |
|
||||
|
||||
## **LiteLLM Python SDK Usage**
|
||||
|
||||
|
|
|
|||
|
|
@ -68,6 +68,7 @@ environment_variables:
|
|||
ARIZE_API_KEY: "141a****"
|
||||
ARIZE_ENDPOINT: "https://otlp.arize.com/v1" # OPTIONAL - your custom arize GRPC api endpoint
|
||||
ARIZE_HTTP_ENDPOINT: "https://otlp.arize.com/v1" # OPTIONAL - your custom arize HTTP api endpoint. Set either this or ARIZE_ENDPOINT or Neither (defaults to https://otlp.arize.com/v1 on grpc)
|
||||
ARIZE_PROJECT_NAME: "my-litellm-project" # OPTIONAL - sets the arize project name
|
||||
```
|
||||
|
||||
2. Start the proxy
|
||||
|
|
|
|||
394
docs/my-website/docs/observability/signoz.md
Normal file
394
docs/my-website/docs/observability/signoz.md
Normal file
|
|
@ -0,0 +1,394 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# SigNoz LiteLLM Integration
|
||||
|
||||
For more details on setting up observability for LiteLLM, check out the [SigNoz LiteLLM observability docs](https://signoz.io/docs/litellm-observability/).
|
||||
|
||||
|
||||
## Overview
|
||||
|
||||
This guide walks you through setting up observability and monitoring for LiteLLM SDK and Proxy Server using [OpenTelemetry](https://opentelemetry.io/) and exporting logs, traces, and metrics to SigNoz. With this integration, you can observe various models performance, capture request/response details, and track system-level metrics in SigNoz, giving you real-time visibility into latency, error rates, and usage trends for your LiteLLM applications.
|
||||
|
||||
Instrumenting LiteLLM in your AI applications with telemetry ensures full observability across your AI workflows, making it easier to debug issues, optimize performance, and understand user interactions. By leveraging SigNoz, you can analyze correlated traces, logs, and metrics in unified dashboards, configure alerts, and gain actionable insights to continuously improve reliability, responsiveness, and user experience.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
- A [SigNoz Cloud account](https://signoz.io/teams/) with an active ingestion key
|
||||
- Internet access to send telemetry data to SigNoz Cloud
|
||||
- [LiteLLM](https://www.litellm.ai/) SDK or Proxy integration
|
||||
- For Python: `pip` installed for managing Python packages and _(optional but recommended)_ a Python virtual environment to isolate dependencies
|
||||
|
||||
## Monitoring LiteLLM
|
||||
|
||||
LiteLLM can be monitored in two ways: using the **LiteLLM SDK** (directly embedded in your Python application code for programmatic LLM calls) or the **LiteLLM Proxy Server** (a standalone server that acts as a centralized gateway for managing and routing LLM requests across your infrastructure).
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="LiteLLM SDK" label="LiteLLM SDK" default>
|
||||
|
||||
For more detailed info on instrumenting your LiteLLM SDK applications click [here](https://docs.litellm.ai/docs/observability/opentelemetry_integration).
|
||||
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="No Code" label="No Code(Recommended)" default>
|
||||
|
||||
No-code auto-instrumentation is recommended for quick setup with minimal code changes. It's ideal when you want to get observability up and running without modifying your application code and are leveraging standard instrumentor libraries.
|
||||
|
||||
**Step 1:** Install the necessary packages in your Python environment.
|
||||
|
||||
```bash
|
||||
pip install \
|
||||
opentelemetry-api \
|
||||
opentelemetry-distro \
|
||||
opentelemetry-exporter-otlp \
|
||||
httpx \
|
||||
opentelemetry-instrumentation-httpx \
|
||||
litellm
|
||||
```
|
||||
|
||||
**Step 2:** Add Automatic Instrumentation
|
||||
|
||||
```bash
|
||||
opentelemetry-bootstrap --action=install
|
||||
```
|
||||
|
||||
**Step 3:** Instrument your LiteLLM SDK application
|
||||
|
||||
Initialize LiteLLM SDK instrumentation by calling `litellm.callbacks = ["otel"]`:
|
||||
|
||||
```python
|
||||
from litellm import litellm
|
||||
|
||||
litellm.callbacks = ["otel"]
|
||||
```
|
||||
|
||||
This call enables automatic tracing, logs, and metrics collection for all LiteLLM SDK calls in your application.
|
||||
|
||||
> 📌 Note: Ensure this is called before any LiteLLM related calls to properly configure instrumentation of your application
|
||||
|
||||
**Step 4:** Run an example
|
||||
|
||||
```python
|
||||
from litellm import completion, litellm
|
||||
|
||||
litellm.callbacks = ["otel"]
|
||||
|
||||
response = completion(
|
||||
model="openai/gpt-4o",
|
||||
messages=[{ "content": "What is SigNoz","role": "user"}]
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
> 📌 Note: LiteLLM supports a [variety of model providers](https://docs.litellm.ai/docs/providers) for LLMs. In this example, we're using OpenAI. Before running this code, ensure that you have set the environment variable `OPENAI_API_KEY` with your generated API key.
|
||||
|
||||
**Step 5:** Run your application with auto-instrumentation
|
||||
|
||||
```bash
|
||||
OTEL_RESOURCE_ATTRIBUTES="service.name=<service_name>" \
|
||||
OTEL_EXPORTER_OTLP_ENDPOINT="https://ingest.<region>.signoz.cloud:443" \
|
||||
OTEL_EXPORTER_OTLP_HEADERS="signoz-ingestion-key=<your_ingestion_key>" \
|
||||
OTEL_EXPORTER_OTLP_PROTOCOL=grpc \
|
||||
OTEL_TRACES_EXPORTER=otlp \
|
||||
OTEL_METRICS_EXPORTER=otlp \
|
||||
OTEL_LOGS_EXPORTER=otlp \
|
||||
OTEL_PYTHON_LOG_CORRELATION=true \
|
||||
OTEL_PYTHON_LOGGING_AUTO_INSTRUMENTATION_ENABLED=true \
|
||||
OTEL_PYTHON_DISABLED_INSTRUMENTATIONS=openai \
|
||||
opentelemetry-instrument <your_run_command>
|
||||
```
|
||||
|
||||
> 📌 Note: We're using `OTEL_PYTHON_DISABLED_INSTRUMENTATIONS=openai` in the run command to disable the OpenAI instrumentor for tracing. This avoids conflicts with LiteLLM's native telemetry/instrumentation, ensuring that telemetry is captured exclusively through LiteLLM's built-in instrumentation.
|
||||
|
||||
- **`<service_name>`** is the name of your service
|
||||
- Set the `<region>` to match your SigNoz Cloud [region](https://signoz.io/docs/ingestion/signoz-cloud/overview/#endpoint)
|
||||
- Replace `<your_ingestion_key>` with your SigNoz [ingestion key](https://signoz.io/docs/ingestion/signoz-cloud/keys/)
|
||||
- Replace `<your_run_command>` with the actual command you would use to run your application. For example: `python main.py`
|
||||
|
||||
> 📌 Note: Using self-hosted SigNoz? Most steps are identical. To adapt this guide, update the endpoint and remove the ingestion key header as shown in [Cloud → Self-Hosted](https://signoz.io/docs/ingestion/cloud-vs-self-hosted/#cloud-to-self-hosted).
|
||||
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="Code" label="Code" default>
|
||||
|
||||
Code-based instrumentation gives you fine-grained control over your telemetry configuration. Use this approach when you need to customize resource attributes, sampling strategies, or integrate with existing observability infrastructure.
|
||||
|
||||
**Step 1:** Install the necessary packages in your Python environment.
|
||||
|
||||
```bash
|
||||
pip install \
|
||||
opentelemetry-api \
|
||||
opentelemetry-sdk \
|
||||
opentelemetry-exporter-otlp \
|
||||
opentelemetry-instrumentation-httpx \
|
||||
opentelemetry-instrumentation-system-metrics \
|
||||
litellm
|
||||
```
|
||||
|
||||
**Step 2:** Import the necessary modules in your Python application
|
||||
|
||||
**Traces:**
|
||||
|
||||
```python
|
||||
from opentelemetry import trace
|
||||
from opentelemetry.sdk.resources import Resource
|
||||
from opentelemetry.sdk.trace import TracerProvider
|
||||
from opentelemetry.sdk.trace.export import BatchSpanProcessor
|
||||
from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter
|
||||
```
|
||||
|
||||
**Logs:**
|
||||
|
||||
```python
|
||||
from opentelemetry.sdk._logs import LoggerProvider, LoggingHandler
|
||||
from opentelemetry.sdk._logs.export import BatchLogRecordProcessor
|
||||
from opentelemetry.exporter.otlp.proto.http._log_exporter import OTLPLogExporter
|
||||
from opentelemetry._logs import set_logger_provider
|
||||
import logging
|
||||
```
|
||||
|
||||
**Metrics:**
|
||||
|
||||
```python
|
||||
from opentelemetry.sdk.metrics import MeterProvider
|
||||
from opentelemetry.exporter.otlp.proto.http.metric_exporter import OTLPMetricExporter
|
||||
from opentelemetry.sdk.metrics.export import PeriodicExportingMetricReader
|
||||
from opentelemetry import metrics
|
||||
from opentelemetry.instrumentation.system_metrics import SystemMetricsInstrumentor
|
||||
from opentelemetry.instrumentation.httpx import HTTPXClientInstrumentor
|
||||
```
|
||||
|
||||
**Step 3:** Set up the OpenTelemetry Tracer Provider to send traces directly to SigNoz Cloud
|
||||
|
||||
```python
|
||||
from opentelemetry.sdk.resources import Resource
|
||||
from opentelemetry.sdk.trace import TracerProvider
|
||||
from opentelemetry.sdk.trace.export import BatchSpanProcessor
|
||||
from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter
|
||||
from opentelemetry import trace
|
||||
import os
|
||||
|
||||
resource = Resource.create({"service.name": "<service_name>"})
|
||||
provider = TracerProvider(resource=resource)
|
||||
span_exporter = OTLPSpanExporter(
|
||||
endpoint= os.getenv("OTEL_EXPORTER_TRACES_ENDPOINT"),
|
||||
headers={"signoz-ingestion-key": os.getenv("SIGNOZ_INGESTION_KEY")},
|
||||
)
|
||||
processor = BatchSpanProcessor(span_exporter)
|
||||
provider.add_span_processor(processor)
|
||||
trace.set_tracer_provider(provider)
|
||||
```
|
||||
|
||||
- **`<service_name>`** is the name of your service
|
||||
- **`OTEL_EXPORTER_TRACES_ENDPOINT`** → SigNoz Cloud trace endpoint with appropriate [region](https://signoz.io/docs/ingestion/signoz-cloud/overview/#endpoint):`https://ingest.<region>.signoz.cloud:443/v1/traces`
|
||||
- **`SIGNOZ_INGESTION_KEY`** → Your SigNoz [ingestion key](https://signoz.io/docs/ingestion/signoz-cloud/keys/)
|
||||
|
||||
|
||||
> 📌 Note: Using self-hosted SigNoz? Most steps are identical. To adapt this guide, update the endpoint and remove the ingestion key header as shown in [Cloud → Self-Hosted](https://signoz.io/docs/ingestion/cloud-vs-self-hosted/#cloud-to-self-hosted).
|
||||
|
||||
|
||||
**Step 4**: Setup Logs
|
||||
|
||||
```python
|
||||
import logging
|
||||
from opentelemetry.sdk.resources import Resource
|
||||
from opentelemetry._logs import set_logger_provider
|
||||
from opentelemetry.sdk._logs import LoggerProvider, LoggingHandler
|
||||
from opentelemetry.sdk._logs.export import BatchLogRecordProcessor
|
||||
from opentelemetry.exporter.otlp.proto.http._log_exporter import OTLPLogExporter
|
||||
import os
|
||||
|
||||
resource = Resource.create({"service.name": "<service_name>"})
|
||||
logger_provider = LoggerProvider(resource=resource)
|
||||
set_logger_provider(logger_provider)
|
||||
|
||||
otlp_log_exporter = OTLPLogExporter(
|
||||
endpoint= os.getenv("OTEL_EXPORTER_LOGS_ENDPOINT"),
|
||||
headers={"signoz-ingestion-key": os.getenv("SIGNOZ_INGESTION_KEY")},
|
||||
)
|
||||
logger_provider.add_log_record_processor(
|
||||
BatchLogRecordProcessor(otlp_log_exporter)
|
||||
)
|
||||
# Attach OTel logging handler to root logger
|
||||
handler = LoggingHandler(level=logging.INFO, logger_provider=logger_provider)
|
||||
logging.basicConfig(level=logging.INFO, handlers=[handler])
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
```
|
||||
|
||||
- **`<service_name>`** is the name of your service
|
||||
- **`OTEL_EXPORTER_LOGS_ENDPOINT`** → SigNoz Cloud endpoint with appropriate [region](https://signoz.io/docs/ingestion/signoz-cloud/overview/#endpoint):`https://ingest.<region>.signoz.cloud:443/v1/logs`
|
||||
- **`SIGNOZ_INGESTION_KEY`** → Your SigNoz [ingestion key](https://signoz.io/docs/ingestion/signoz-cloud/keys/)
|
||||
|
||||
> 📌 Note: Using self-hosted SigNoz? Most steps are identical. To adapt this guide, update the endpoint and remove the ingestion key header as shown in [Cloud → Self-Hosted](https://signoz.io/docs/ingestion/cloud-vs-self-hosted/#cloud-to-self-hosted).
|
||||
|
||||
|
||||
**Step 5**: Setup Metrics
|
||||
|
||||
```python
|
||||
from opentelemetry.sdk.resources import Resource
|
||||
from opentelemetry.sdk.metrics import MeterProvider
|
||||
from opentelemetry.exporter.otlp.proto.http.metric_exporter import OTLPMetricExporter
|
||||
from opentelemetry.sdk.metrics.export import PeriodicExportingMetricReader
|
||||
from opentelemetry import metrics
|
||||
from opentelemetry.instrumentation.system_metrics import SystemMetricsInstrumentor
|
||||
import os
|
||||
|
||||
resource = Resource.create({"service.name": "<service-name>"})
|
||||
metric_exporter = OTLPMetricExporter(
|
||||
endpoint= os.getenv("OTEL_EXPORTER_METRICS_ENDPOINT"),
|
||||
headers={"signoz-ingestion-key": os.getenv("SIGNOZ_INGESTION_KEY")},
|
||||
)
|
||||
reader = PeriodicExportingMetricReader(metric_exporter)
|
||||
metric_provider = MeterProvider(metric_readers=[reader], resource=resource)
|
||||
metrics.set_meter_provider(metric_provider)
|
||||
|
||||
meter = metrics.get_meter(__name__)
|
||||
|
||||
# turn on out-of-the-box metrics
|
||||
SystemMetricsInstrumentor().instrument()
|
||||
HTTPXClientInstrumentor().instrument()
|
||||
```
|
||||
|
||||
- **`<service_name>`** is the name of your service
|
||||
- **`OTEL_EXPORTER_METRICS_ENDPOINT`** → SigNoz Cloud endpoint with appropriate [region](https://signoz.io/docs/ingestion/signoz-cloud/overview/#endpoint):`https://ingest.<region>.signoz.cloud:443/v1/metrics`
|
||||
- **`SIGNOZ_INGESTION_KEY`** → Your SigNoz [ingestion key](https://signoz.io/docs/ingestion/signoz-cloud/keys/)
|
||||
|
||||
> 📌 Note: Using self-hosted SigNoz? Most steps are identical. To adapt this guide, update the endpoint and remove the ingestion key header as shown in [Cloud → Self-Hosted](https://signoz.io/docs/ingestion/cloud-vs-self-hosted/#cloud-to-self-hosted).
|
||||
|
||||
|
||||
> 📌 Note: SystemMetricsInstrumentor provides system metrics (CPU, memory, etc.), and HTTPXClientInstrumentor provides outbound HTTP request metrics such as request duration. If you want to add custom metrics to your LiteLLM application, see [Python Custom Metrics](https://signoz.io/opentelemetry/python-custom-metrics/).
|
||||
|
||||
**Step 6:** Instrument your LiteLLM application
|
||||
|
||||
Initialize LiteLLM SDK instrumentation by calling `litellm.callbacks = ["otel"]`:
|
||||
|
||||
```python
|
||||
from litellm import litellm
|
||||
|
||||
litellm.callbacks = ["otel"]
|
||||
```
|
||||
|
||||
This call enables automatic tracing, logs, and metrics collection for all LiteLLM SDK calls in your application.
|
||||
|
||||
> 📌 Note: Ensure this is called before any LiteLLM related calls to properly configure instrumentation of your application
|
||||
|
||||
**Step 7:** Run an example
|
||||
|
||||
```python
|
||||
from litellm import completion, litellm
|
||||
|
||||
litellm.callbacks = ["otel"]
|
||||
|
||||
response = completion(
|
||||
model="openai/gpt-4o",
|
||||
messages=[{ "content": "What is SigNoz","role": "user"}]
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
> 📌 Note: LiteLLM supports a [variety of model providers](https://docs.litellm.ai/docs/providers) for LLMs. In this example, we're using OpenAI. Before running this code, ensure that you have set the environment variable `OPENAI_API_KEY` with your generated API key.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## View Traces, Logs, and Metrics in SigNoz
|
||||
|
||||
Your LiteLLM commands should now automatically emit traces, logs, and metrics.
|
||||
|
||||
You should be able to view traces in Signoz Cloud under the traces tab:
|
||||
|
||||
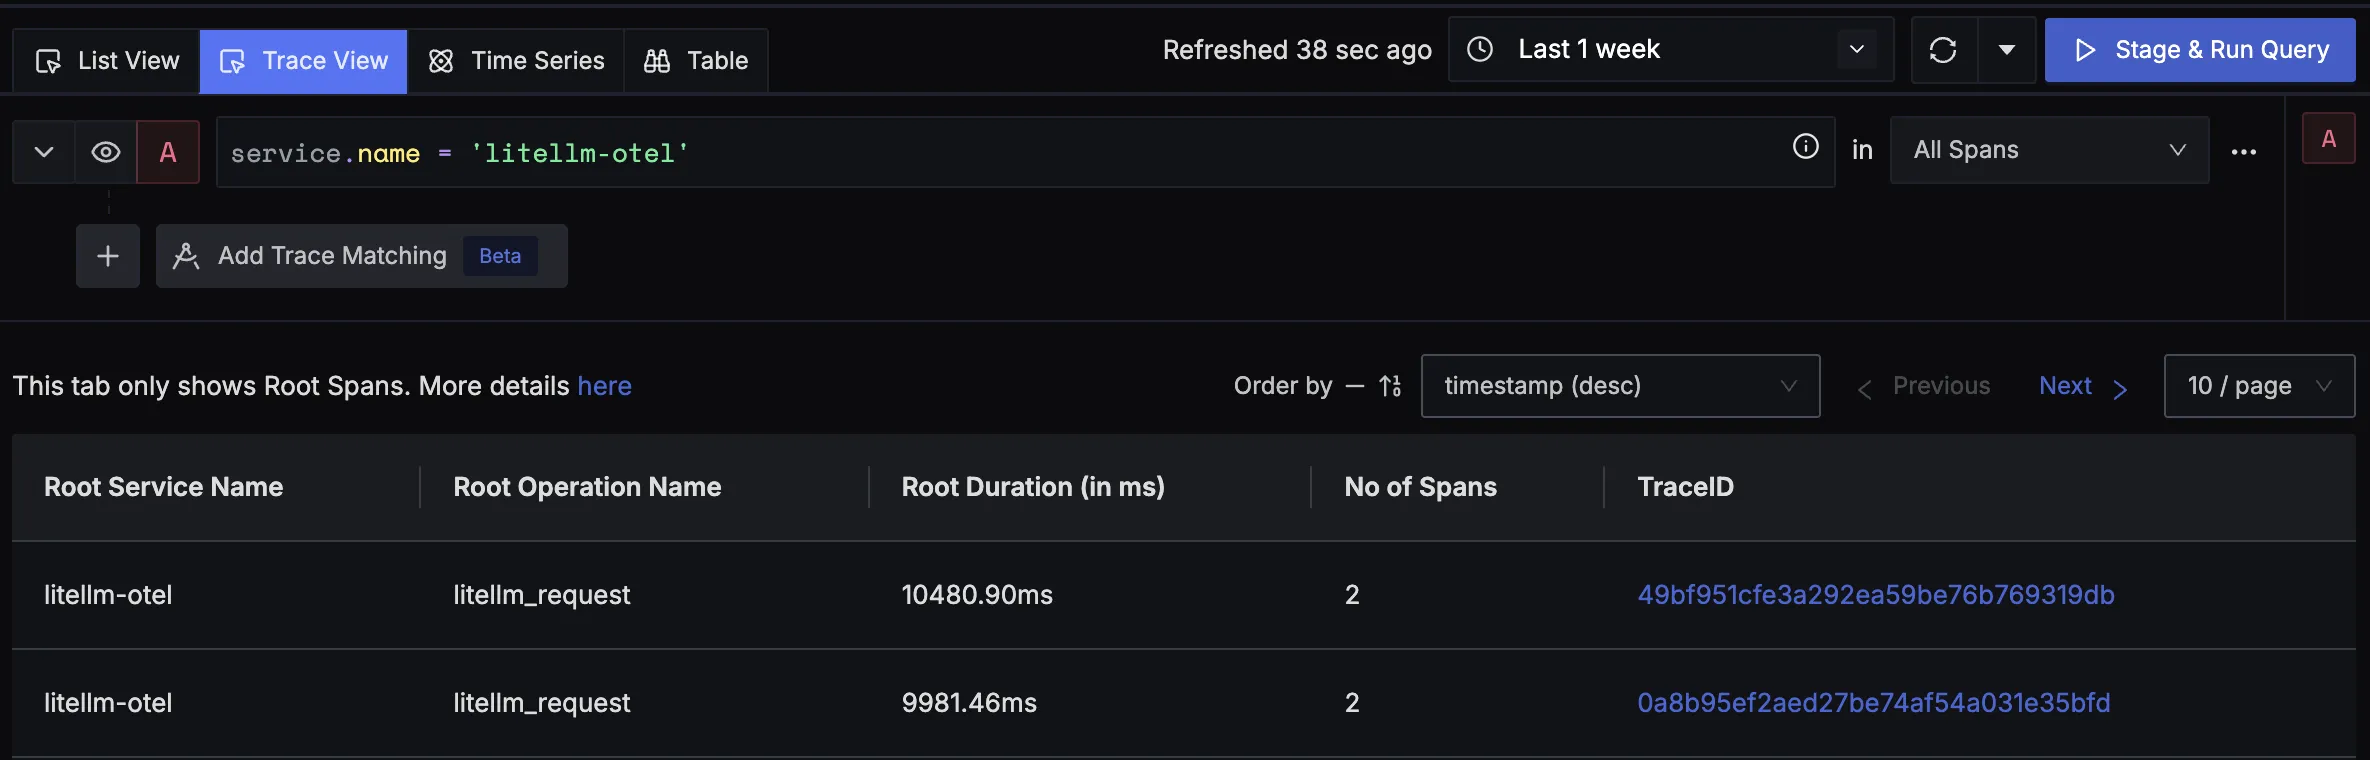
|
||||
|
||||
When you click on a trace in SigNoz, you'll see a detailed view of the trace, including all associated spans, along with their events and attributes.
|
||||
|
||||
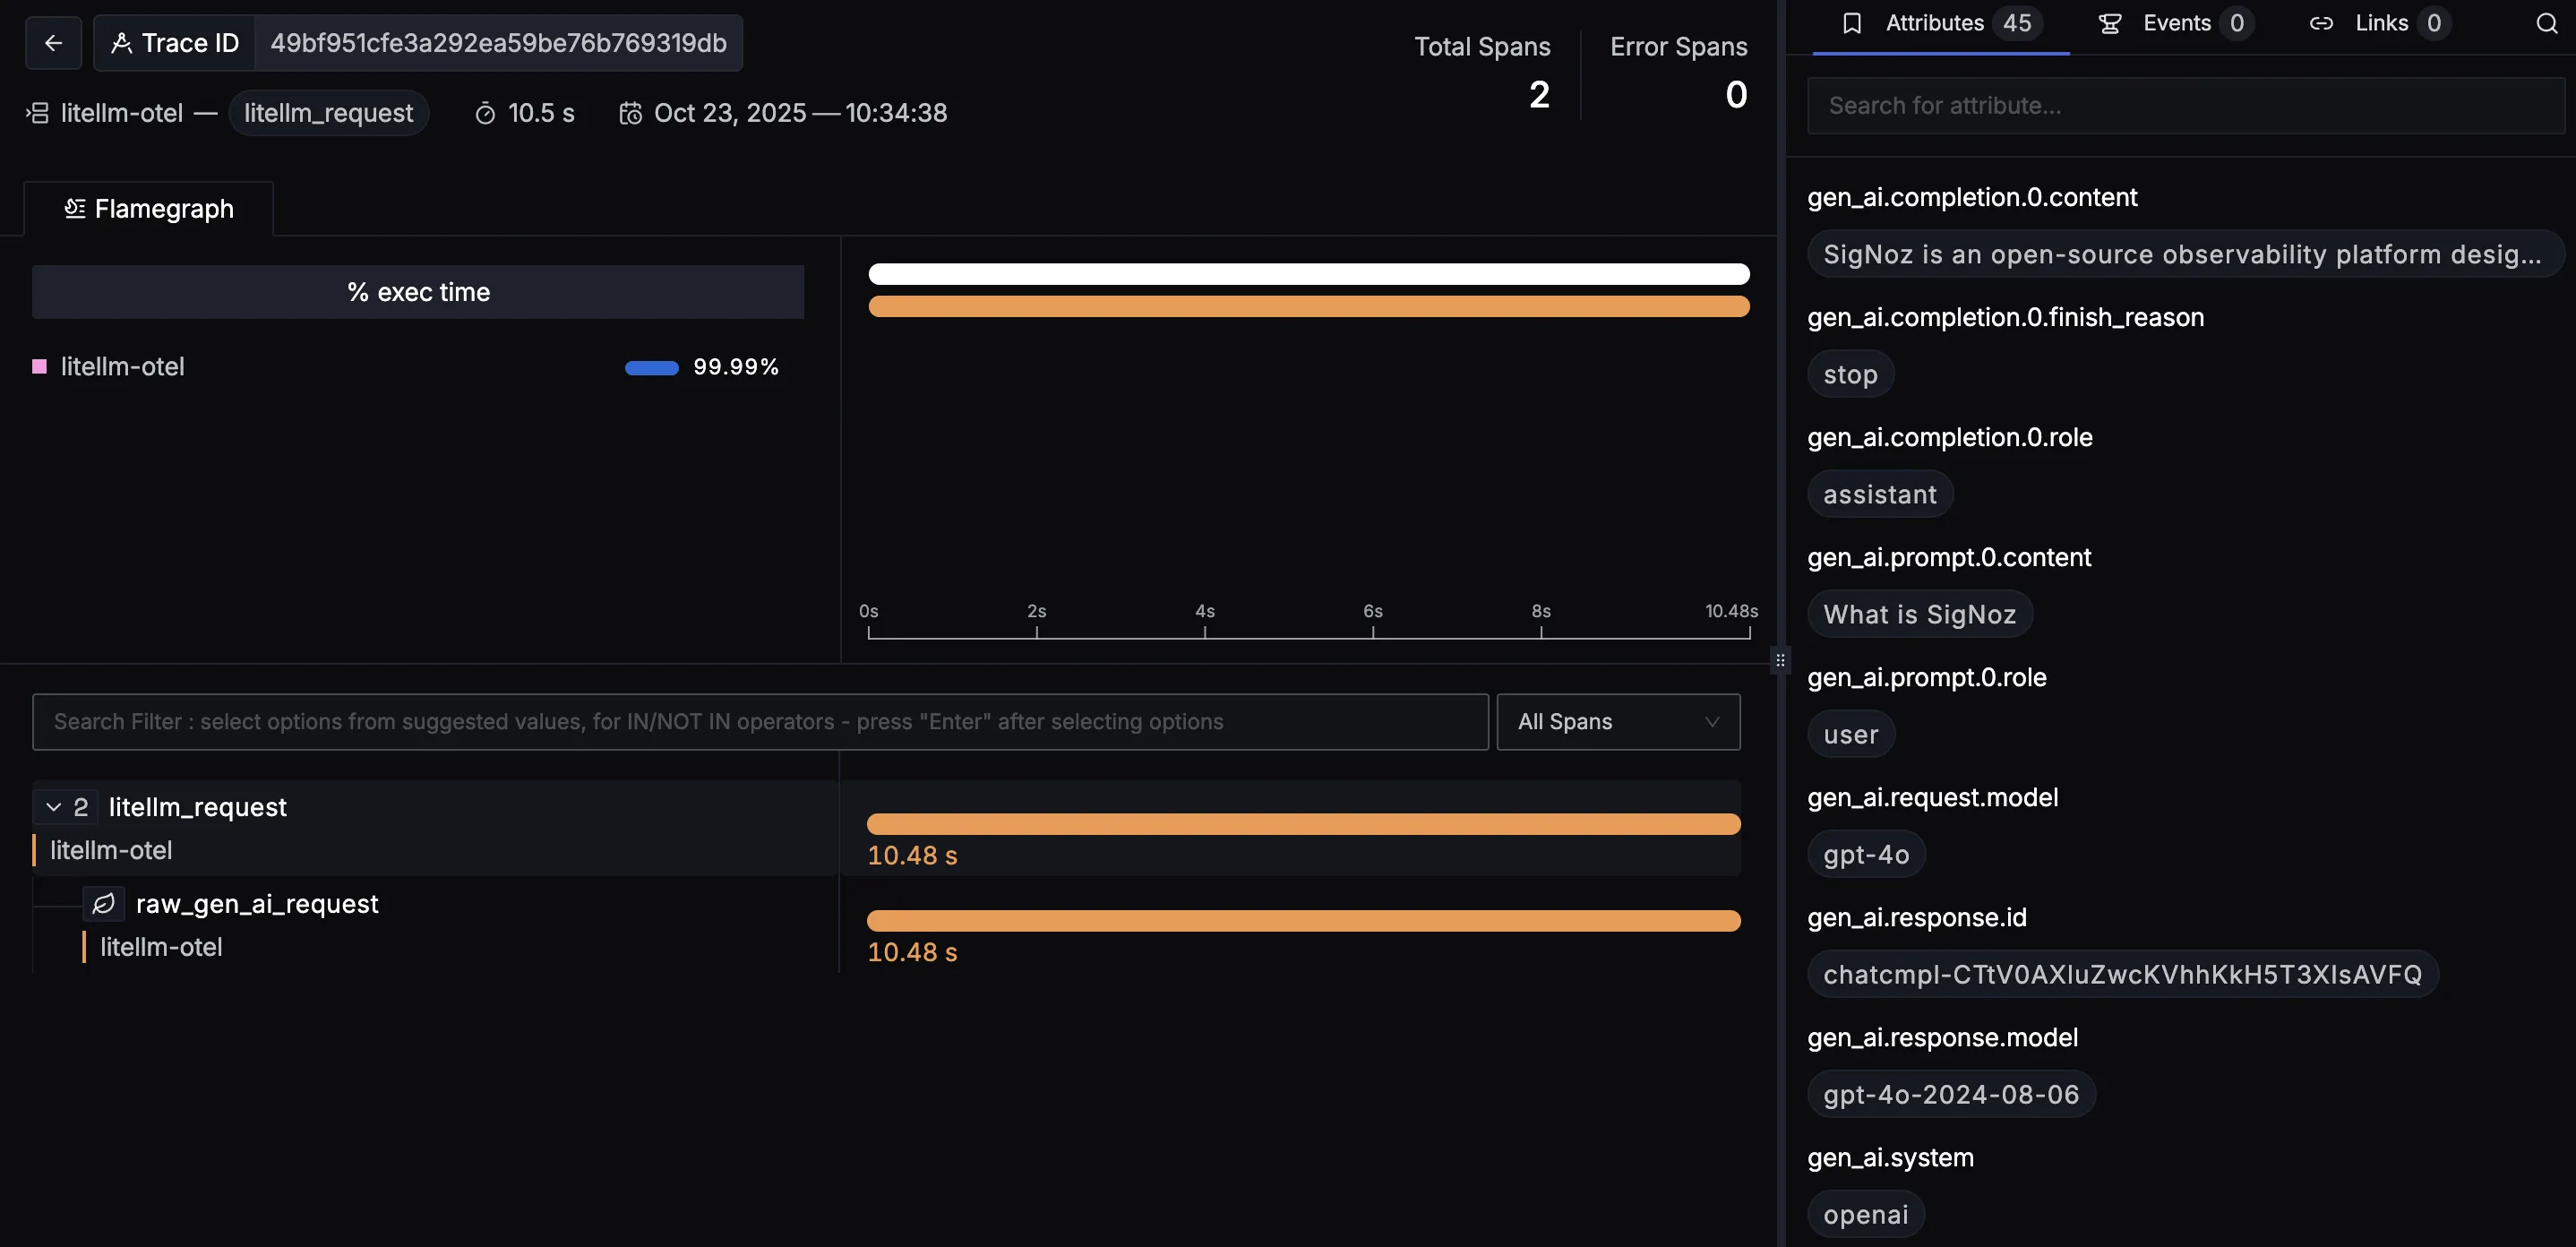
|
||||
|
||||
You should be able to view logs in Signoz Cloud under the logs tab. You can also view logs by clicking on the “Related Logs” button in the trace view to see correlated logs:
|
||||
|
||||
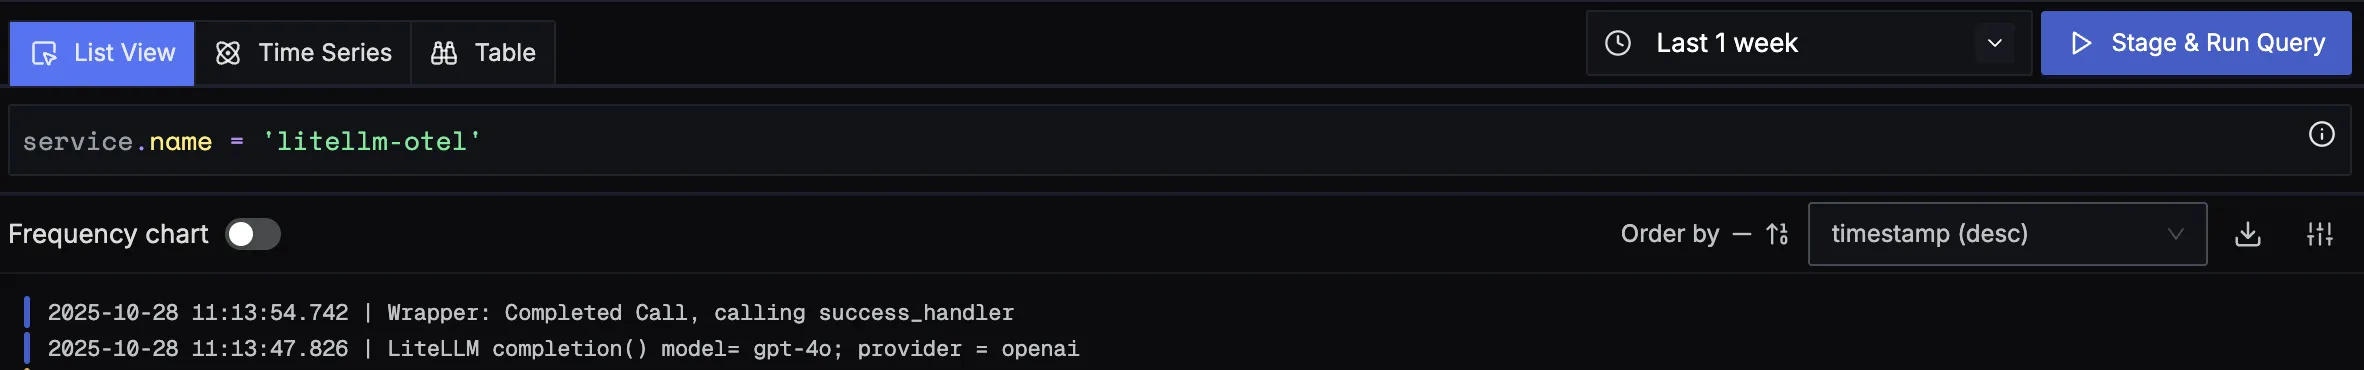
|
||||
|
||||
When you click on any of these logs in SigNoz, you'll see a detailed view of the log, including attributes:
|
||||
|
||||
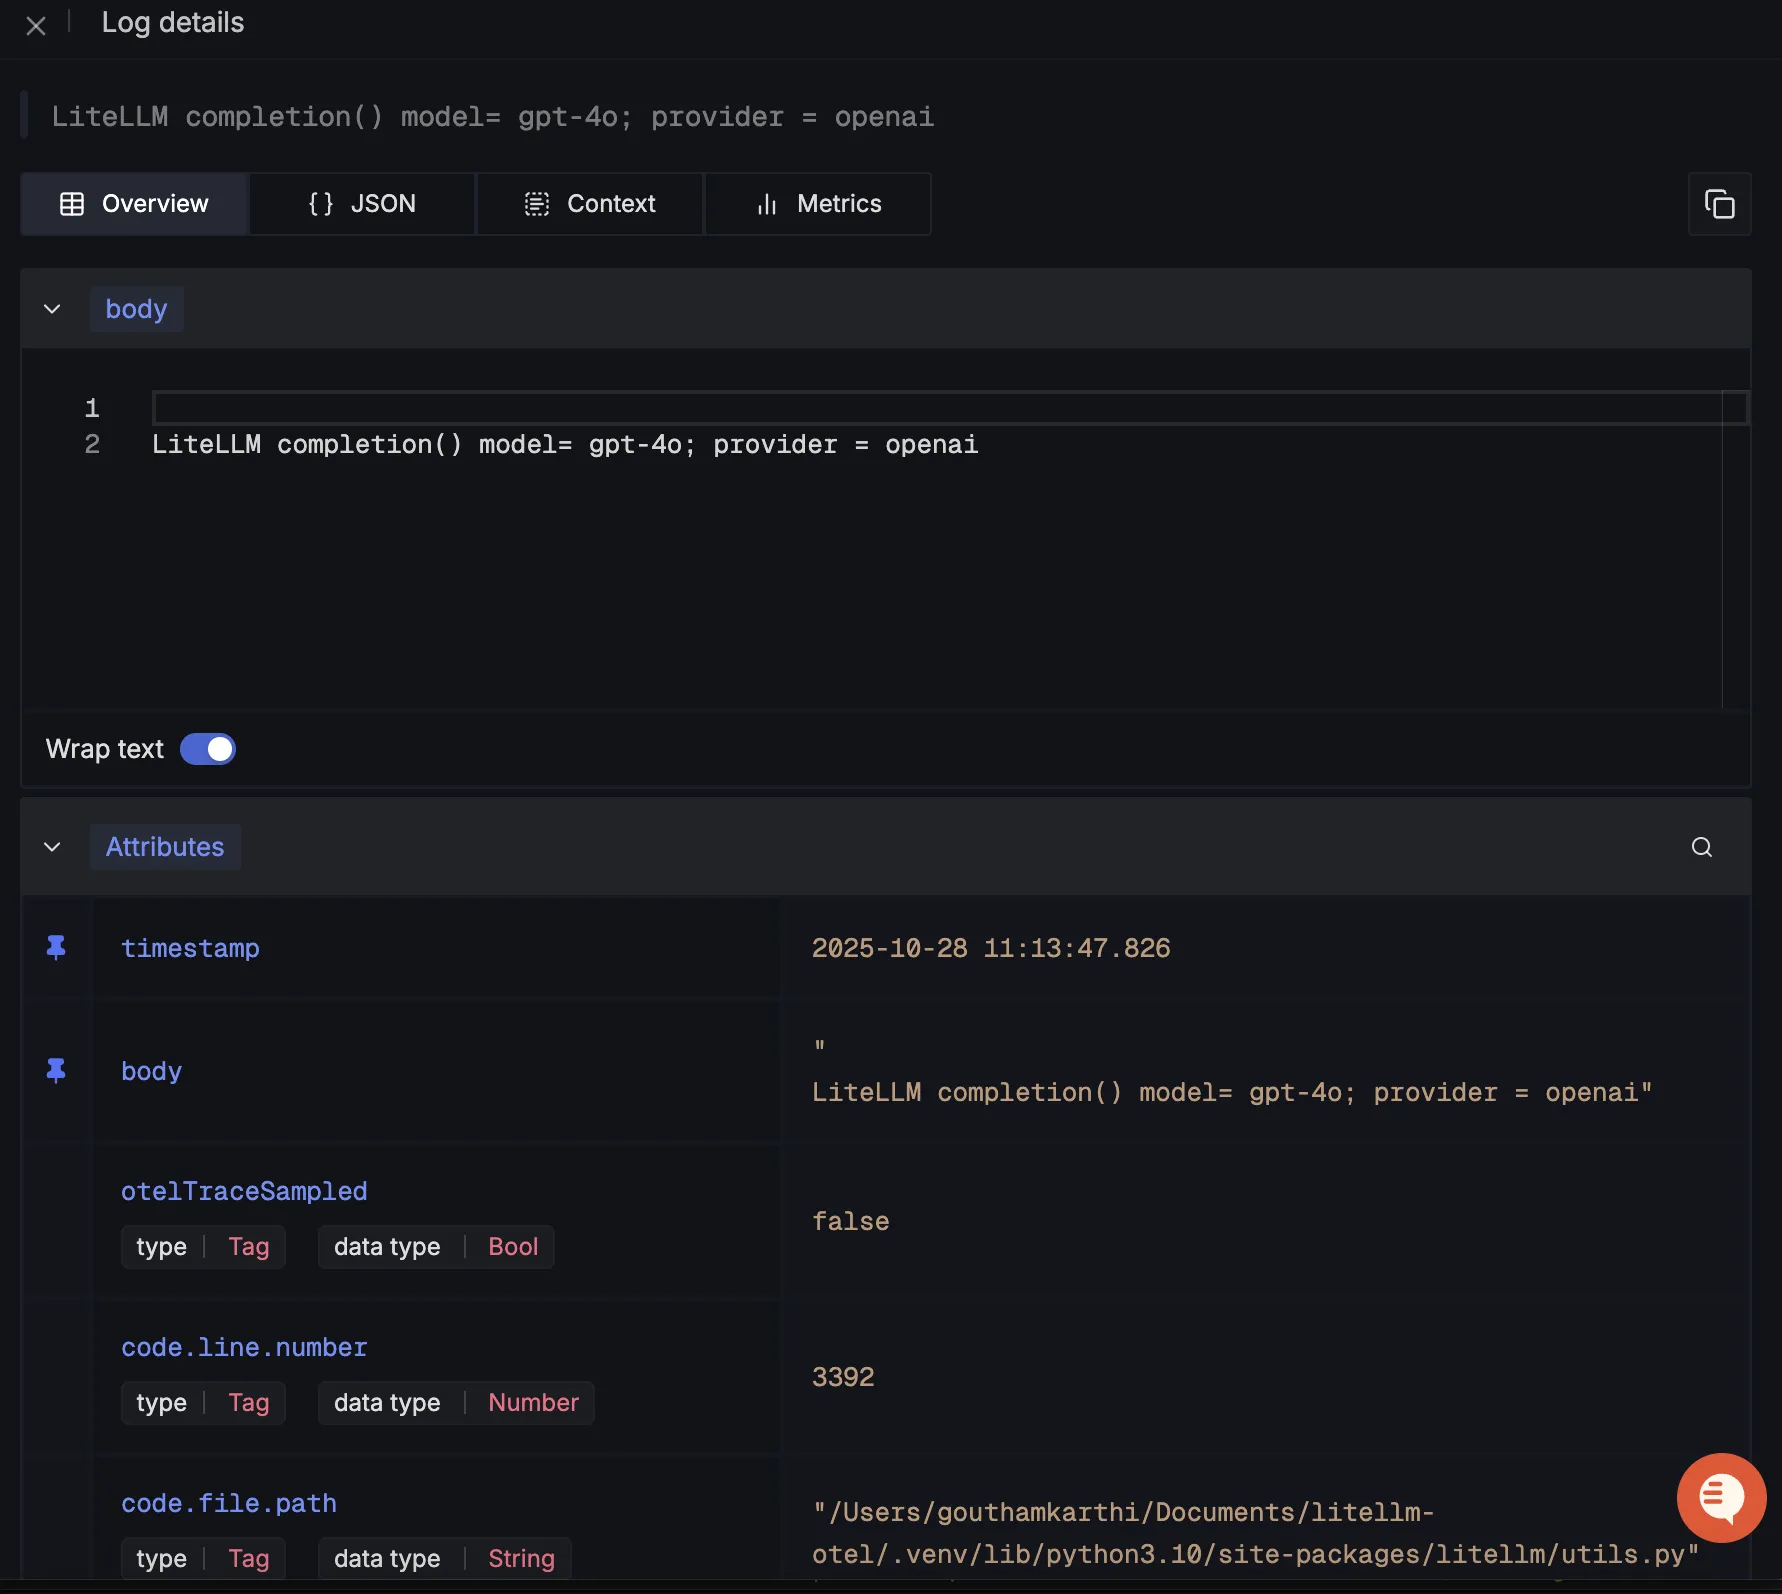
|
||||
|
||||
You should be able to see LiteLLM related metrics in Signoz Cloud under the metrics tab:
|
||||
|
||||
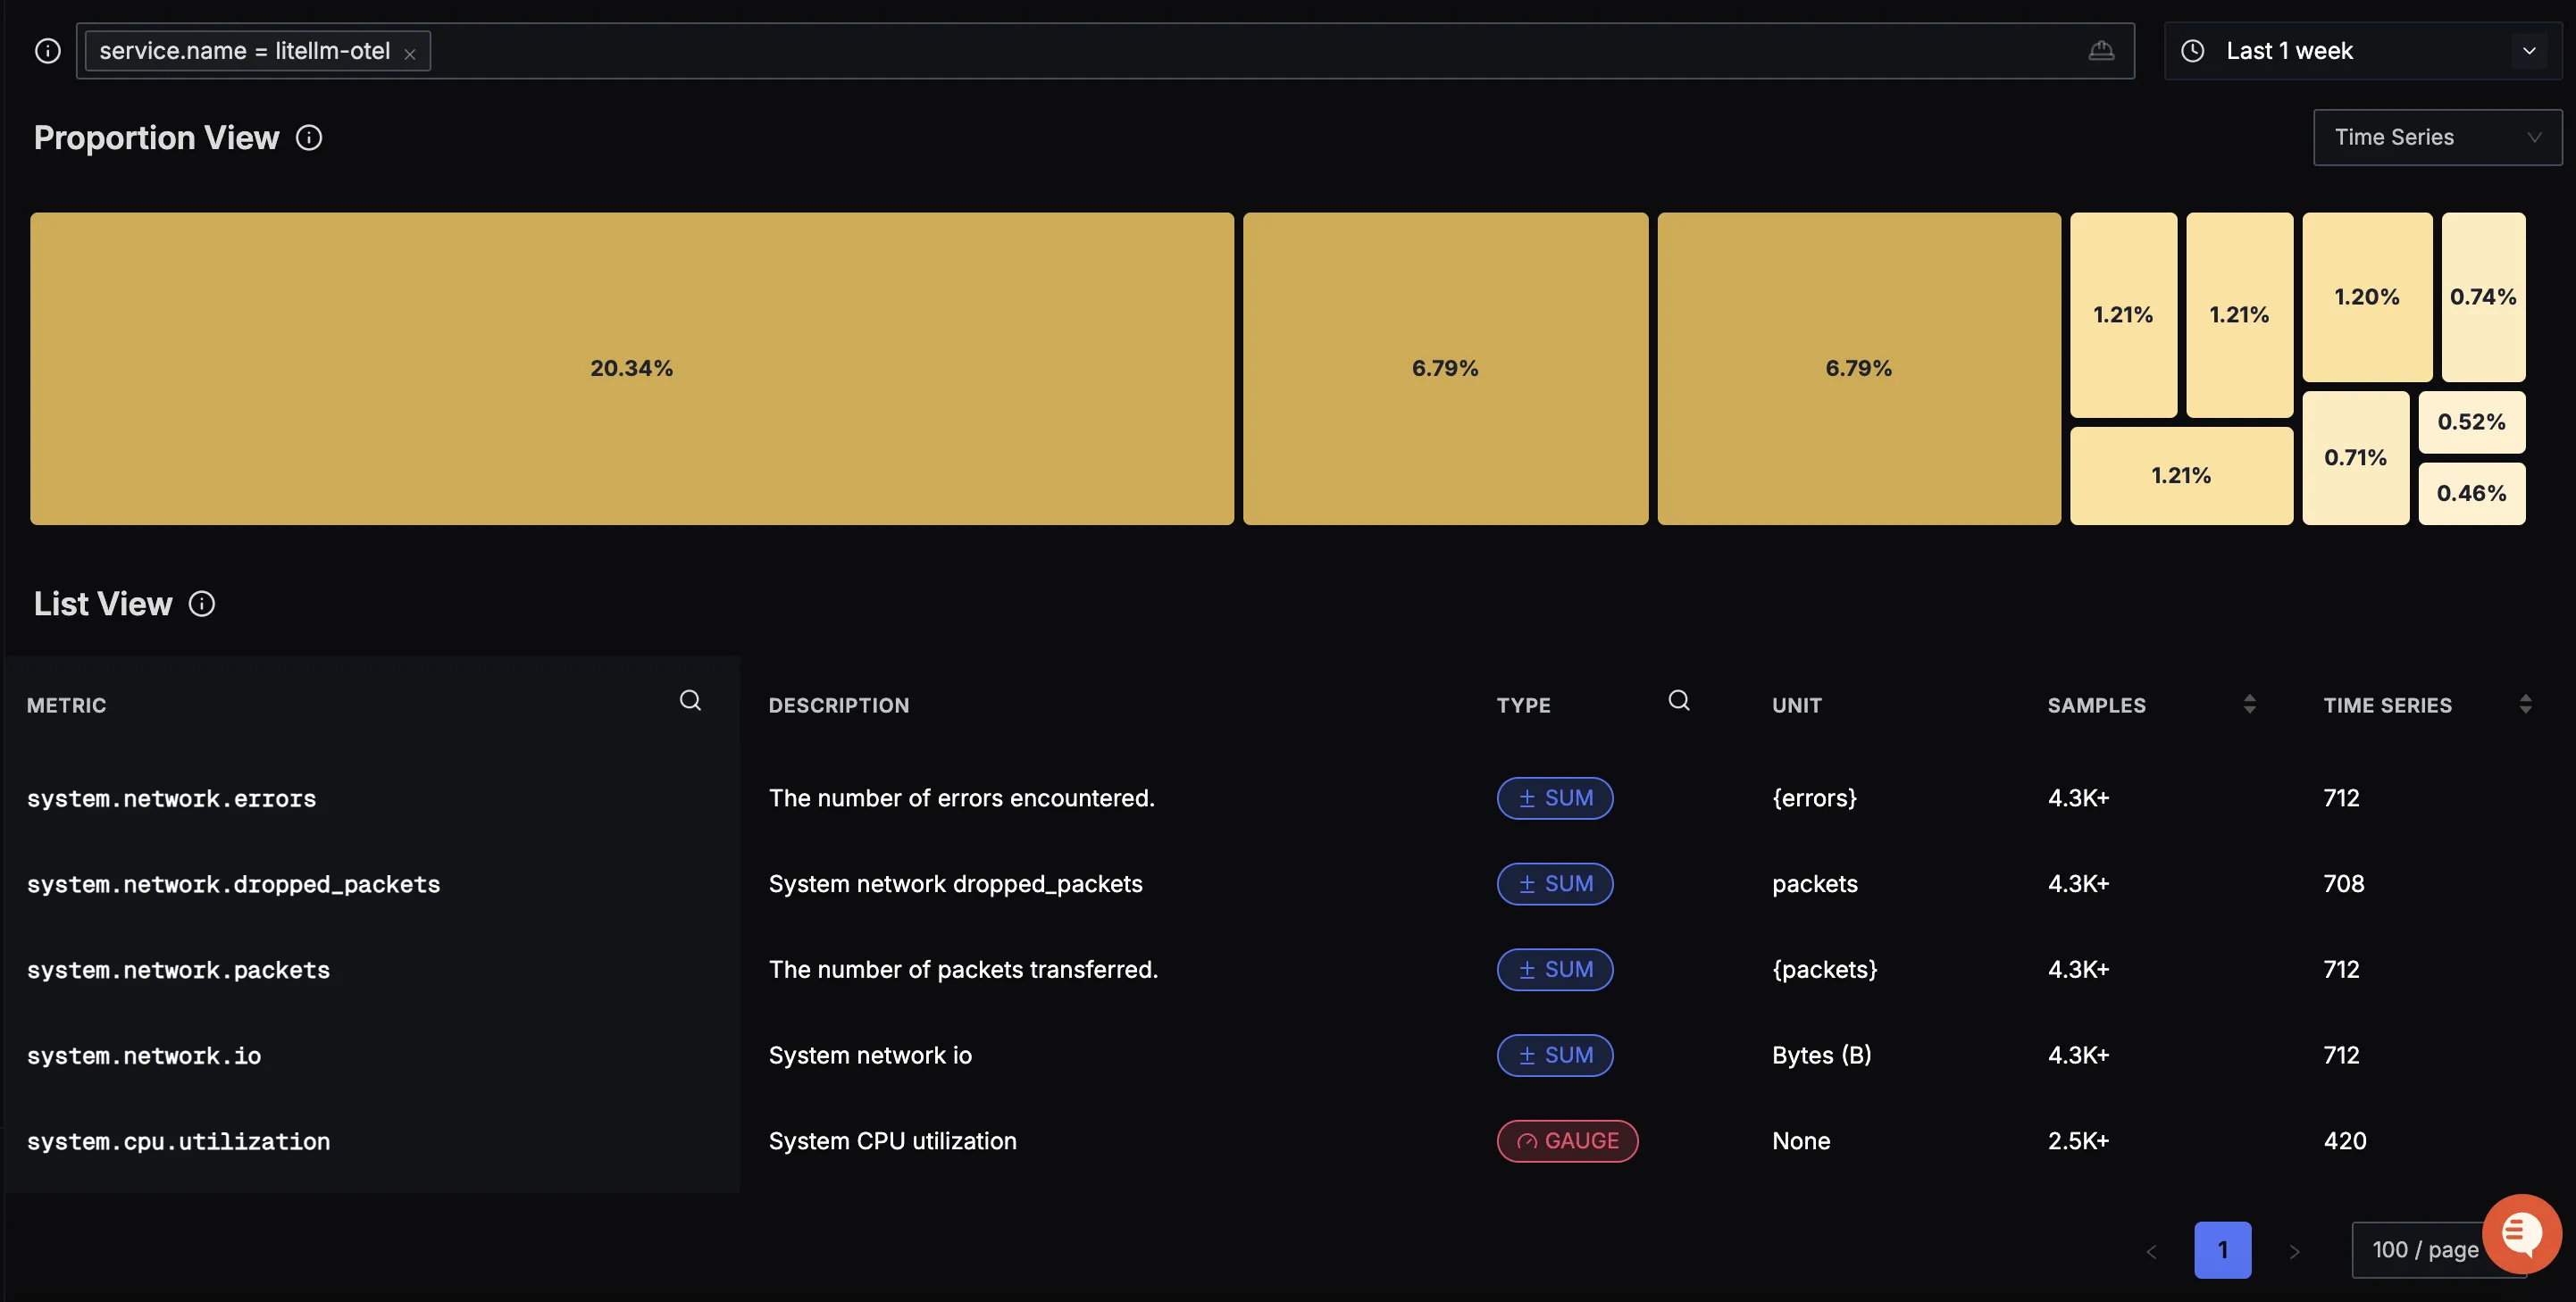
|
||||
|
||||
When you click on any of these metrics in SigNoz, you'll see a detailed view of the metric, including attributes:
|
||||
|
||||
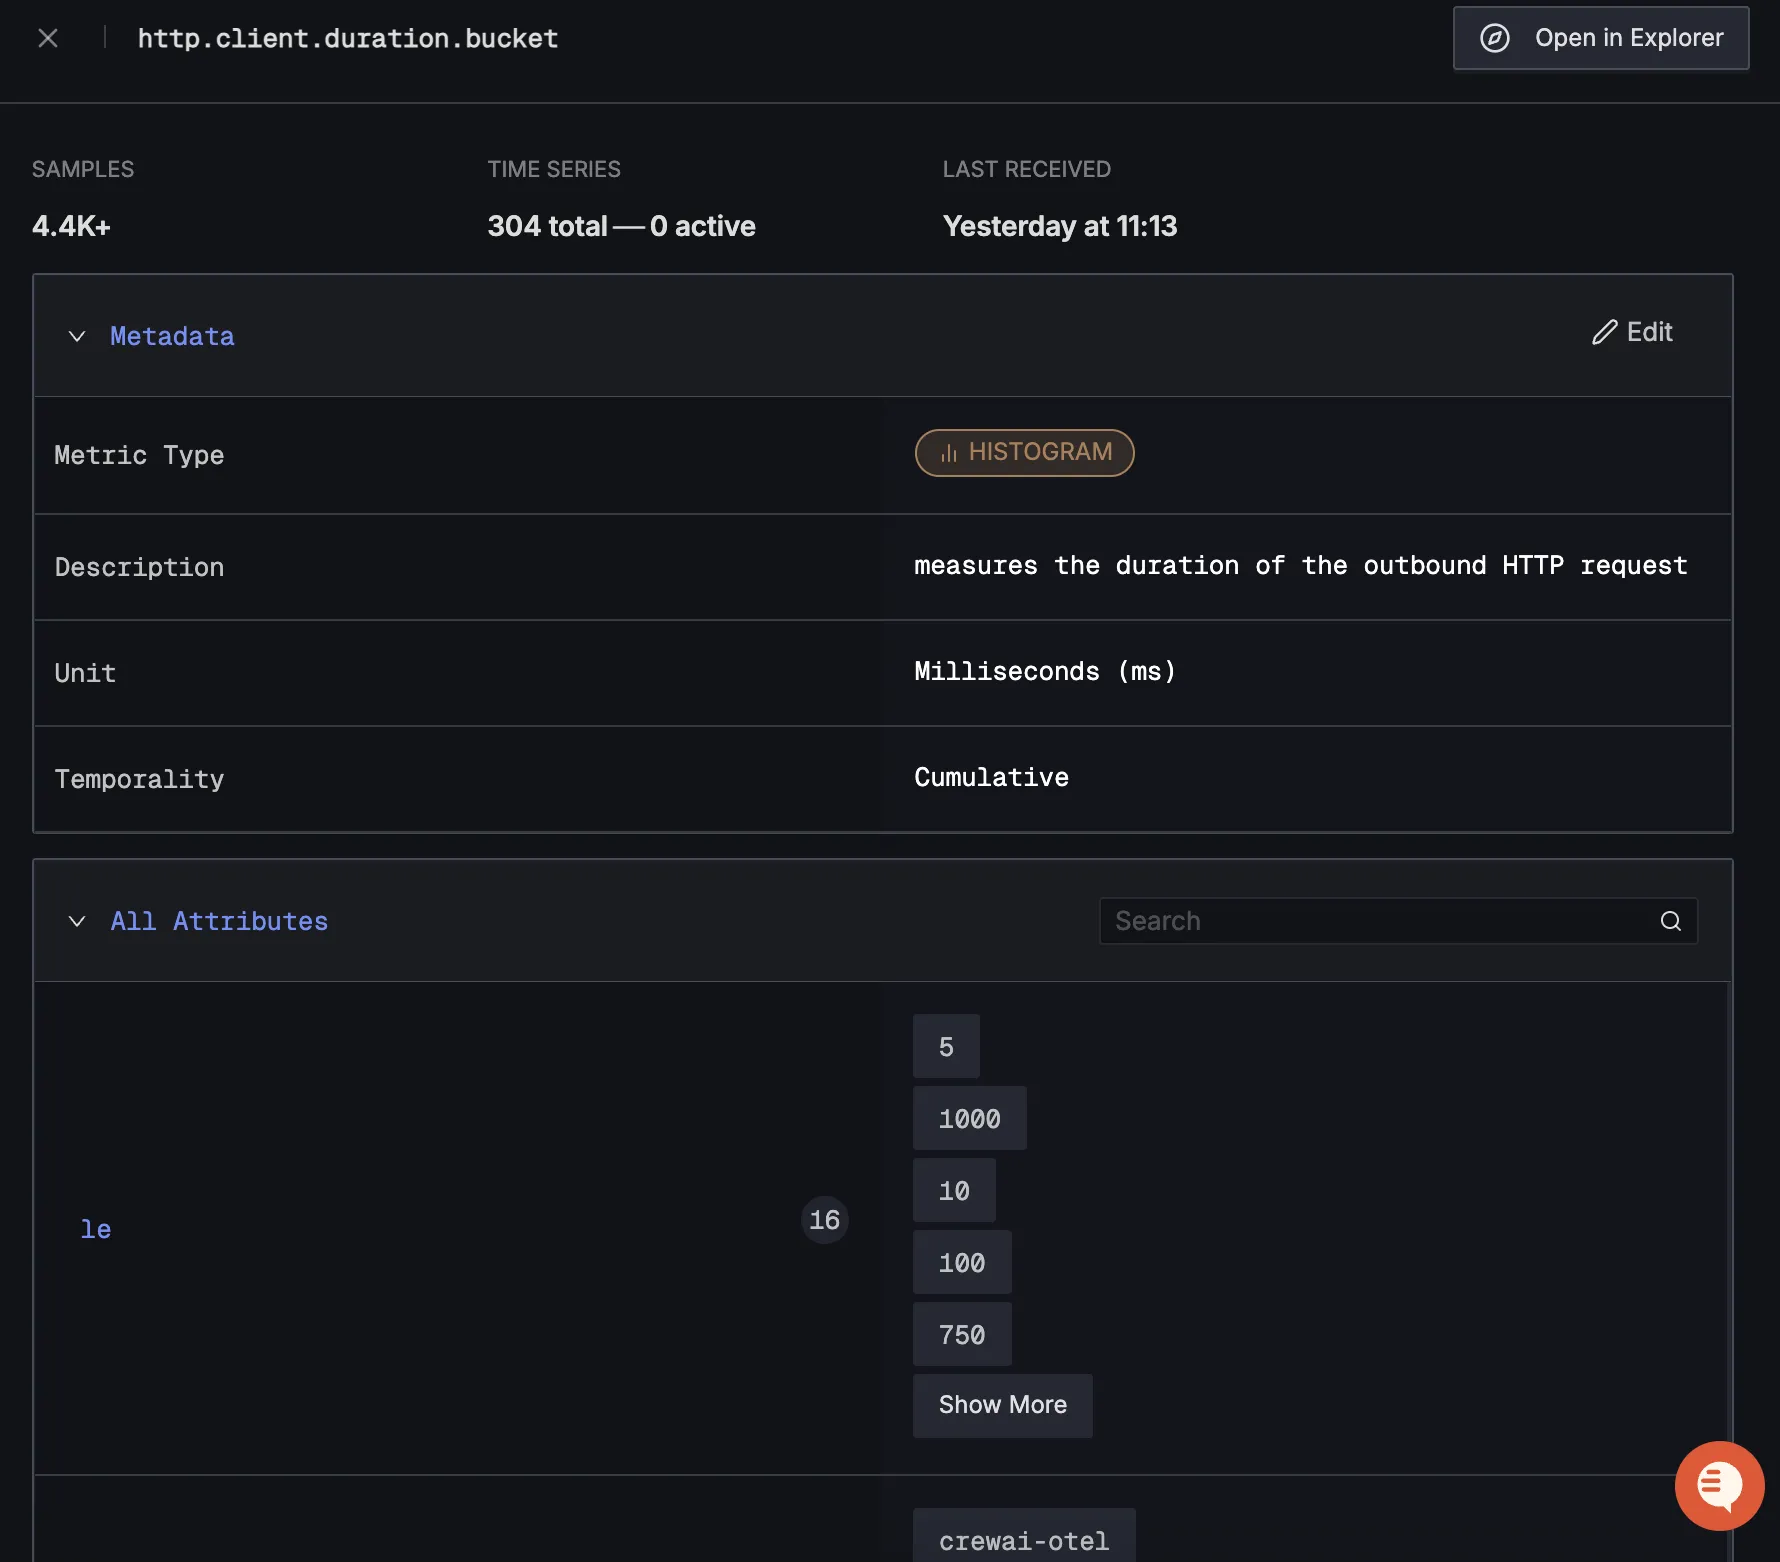
|
||||
|
||||
## Dashboard
|
||||
|
||||
You can also check out our custom LiteLLM SDK dashboard [here](https://signoz.io/docs/dashboards/dashboard-templates/litellm-sdk-dashboard/) which provides specialized visualizations for monitoring your LiteLLM usage in applications. The dashboard includes pre-built charts specifically tailored for LLM usage, along with import instructions to get started quickly.
|
||||
|
||||
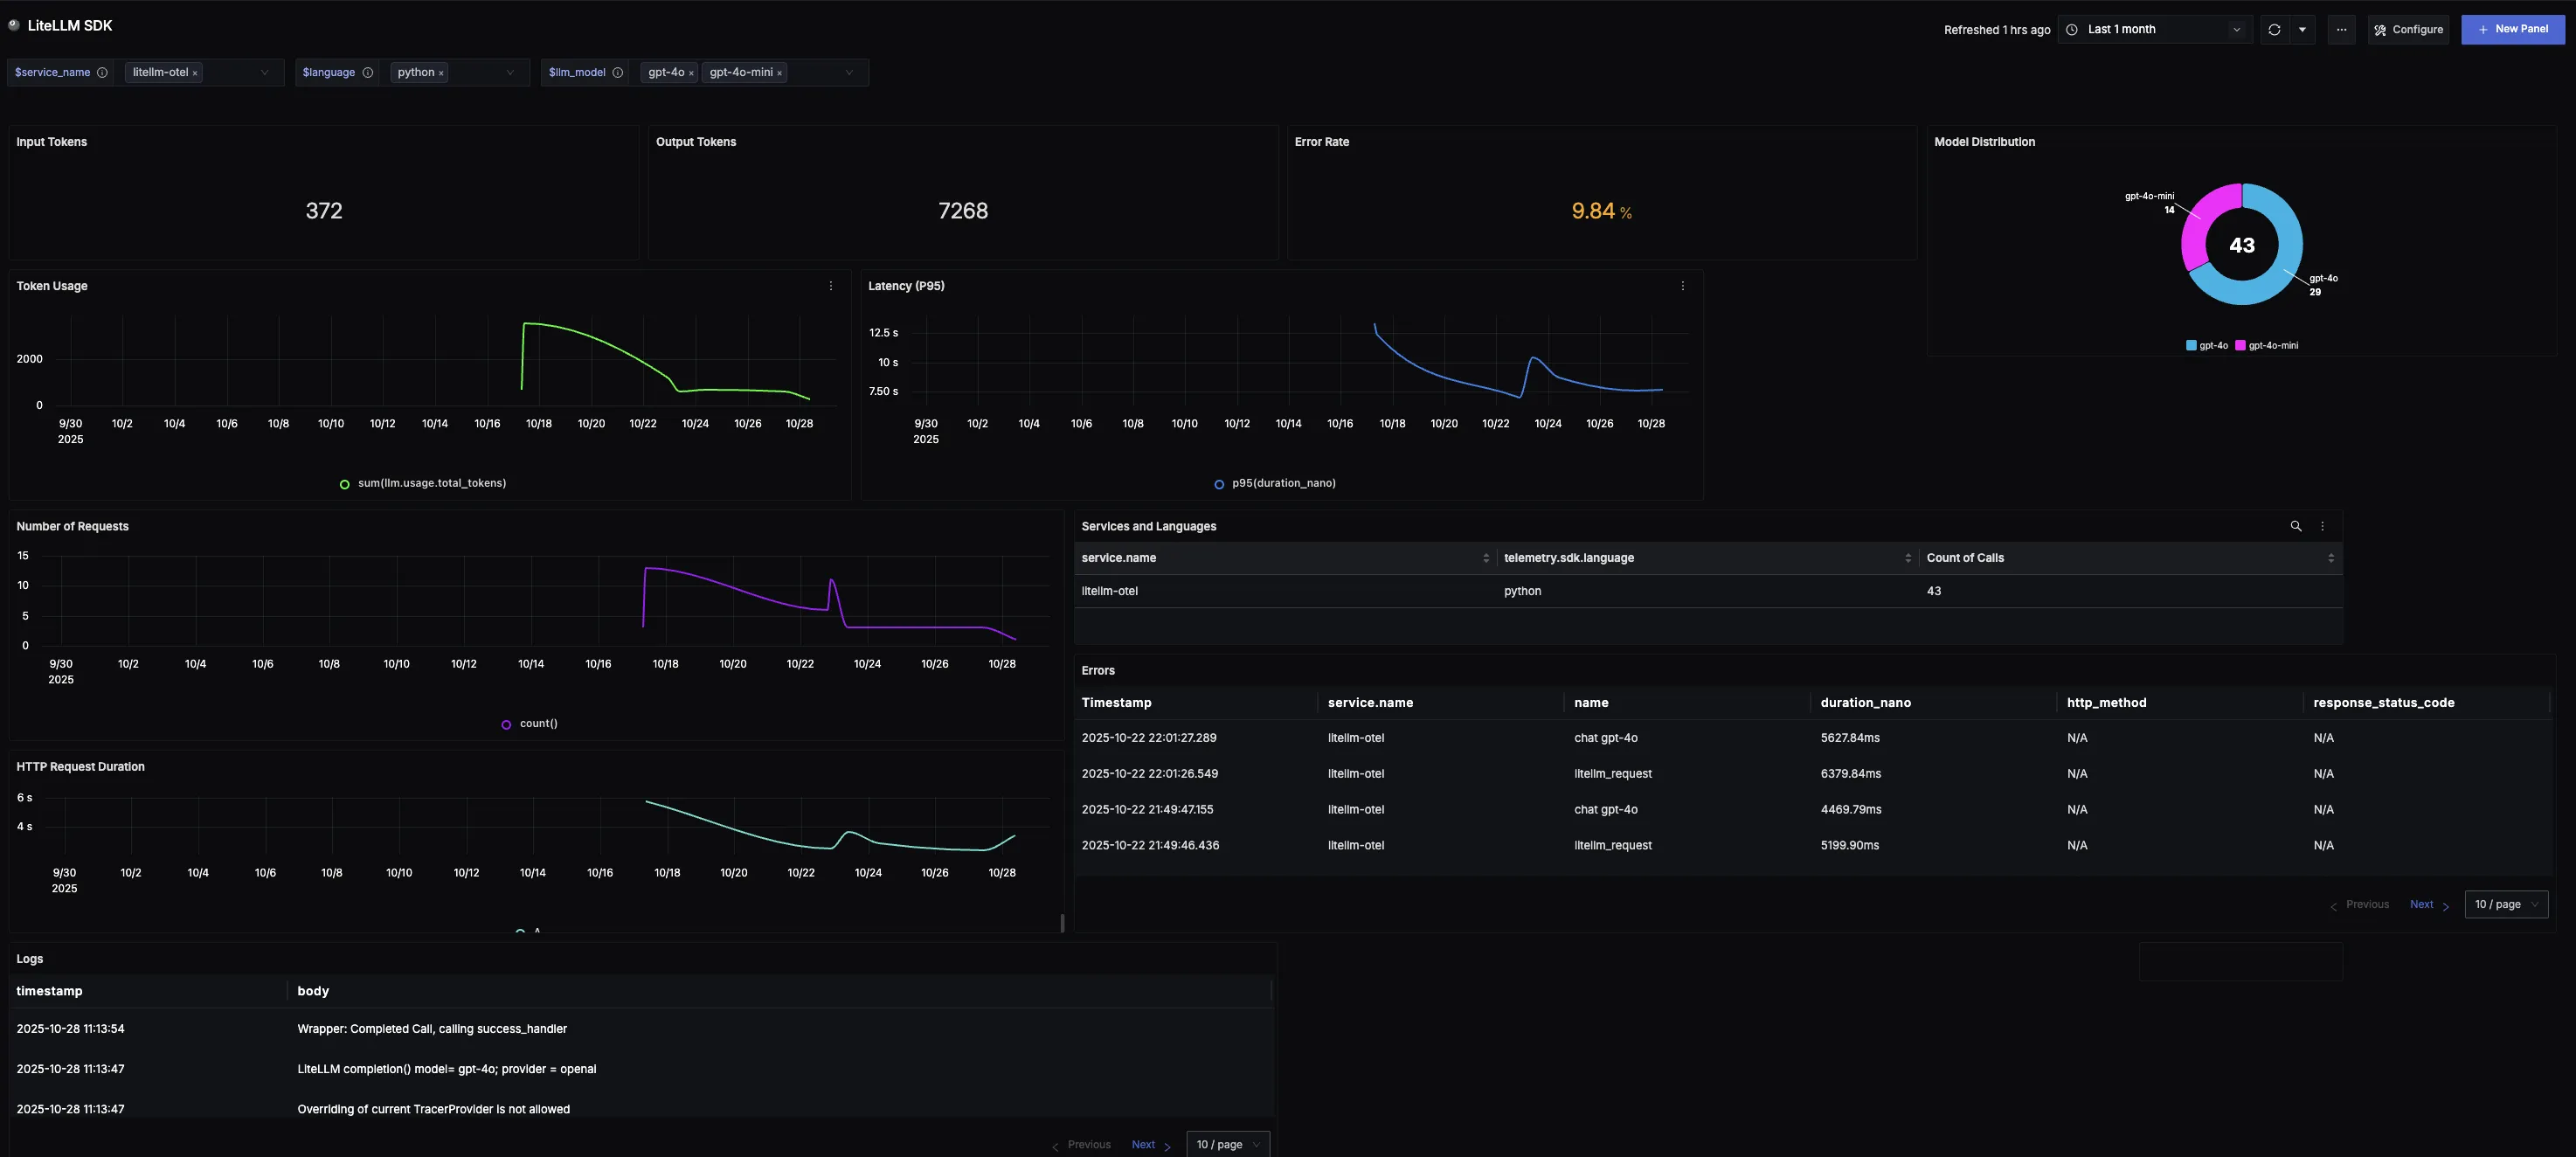
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="LiteLLM Proxy Server" label="LiteLLM Proxy Server" default>
|
||||
|
||||
**Step 1:** Install the necessary packages in your Python environment.
|
||||
|
||||
```bash
|
||||
pip install opentelemetry-api \
|
||||
opentelemetry-sdk \
|
||||
opentelemetry-exporter-otlp \
|
||||
'litellm[proxy]'
|
||||
```
|
||||
|
||||
**Step 2:** Configure otel for the LiteLLM Proxy Server
|
||||
|
||||
Add the following to `config.yaml`:
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
callbacks: ['otel']
|
||||
```
|
||||
|
||||
**Step 3:** Set the following environment variables:
|
||||
|
||||
```bash
|
||||
export OTEL_EXPORTER_OTLP_ENDPOINT="https://ingest.<region>.signoz.cloud:443"
|
||||
export OTEL_EXPORTER_OTLP_HEADERS="signoz-ingestion-key=<your_ingestion_key>"
|
||||
export OTEL_EXPORTER_OTLP_PROTOCOL="grpc"
|
||||
export OTEL_TRACES_EXPORTER="otlp"
|
||||
export OTEL_METRICS_EXPORTER="otlp"
|
||||
export OTEL_LOGS_EXPORTER="otlp"
|
||||
```
|
||||
|
||||
- Set the `<region>` to match your SigNoz Cloud [region](https://signoz.io/docs/ingestion/signoz-cloud/overview/#endpoint)
|
||||
- Replace `<your_ingestion_key>` with your SigNoz [ingestion key](https://signoz.io/docs/ingestion/signoz-cloud/keys/)
|
||||
|
||||
> 📌 Note: Using self-hosted SigNoz? Most steps are identical. To adapt this guide, update the endpoint and remove the ingestion key header as shown in [Cloud → Self-Hosted](https://signoz.io/docs/ingestion/cloud-vs-self-hosted/#cloud-to-self-hosted).
|
||||
|
||||
|
||||
**Step 4:** Run the proxy server using the config file:
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
Now any calls made through your LiteLLM proxy server will be traced and sent to SigNoz.
|
||||
|
||||
You should be able to view traces in Signoz Cloud under the traces tab:
|
||||
|
||||
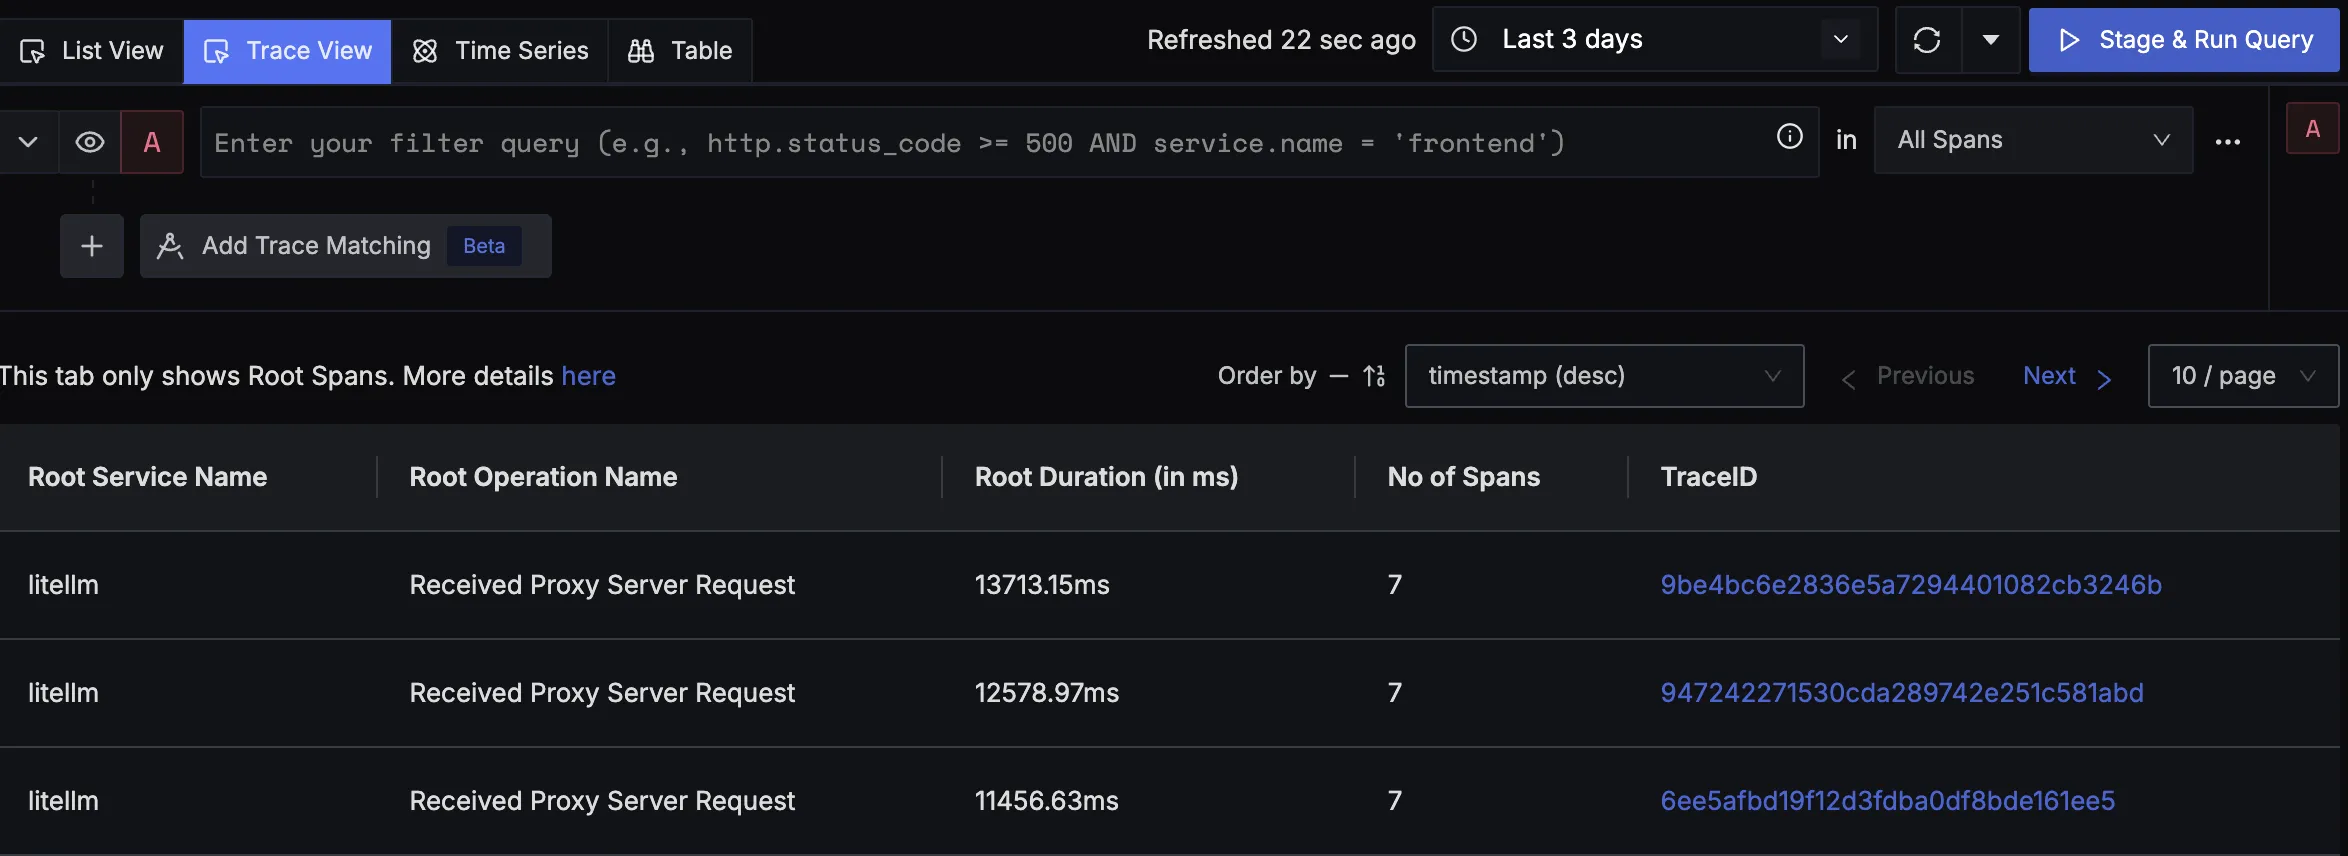
|
||||
|
||||
When you click on a trace in SigNoz, you'll see a detailed view of the trace, including all associated spans, along with their events and attributes.
|
||||
|
||||
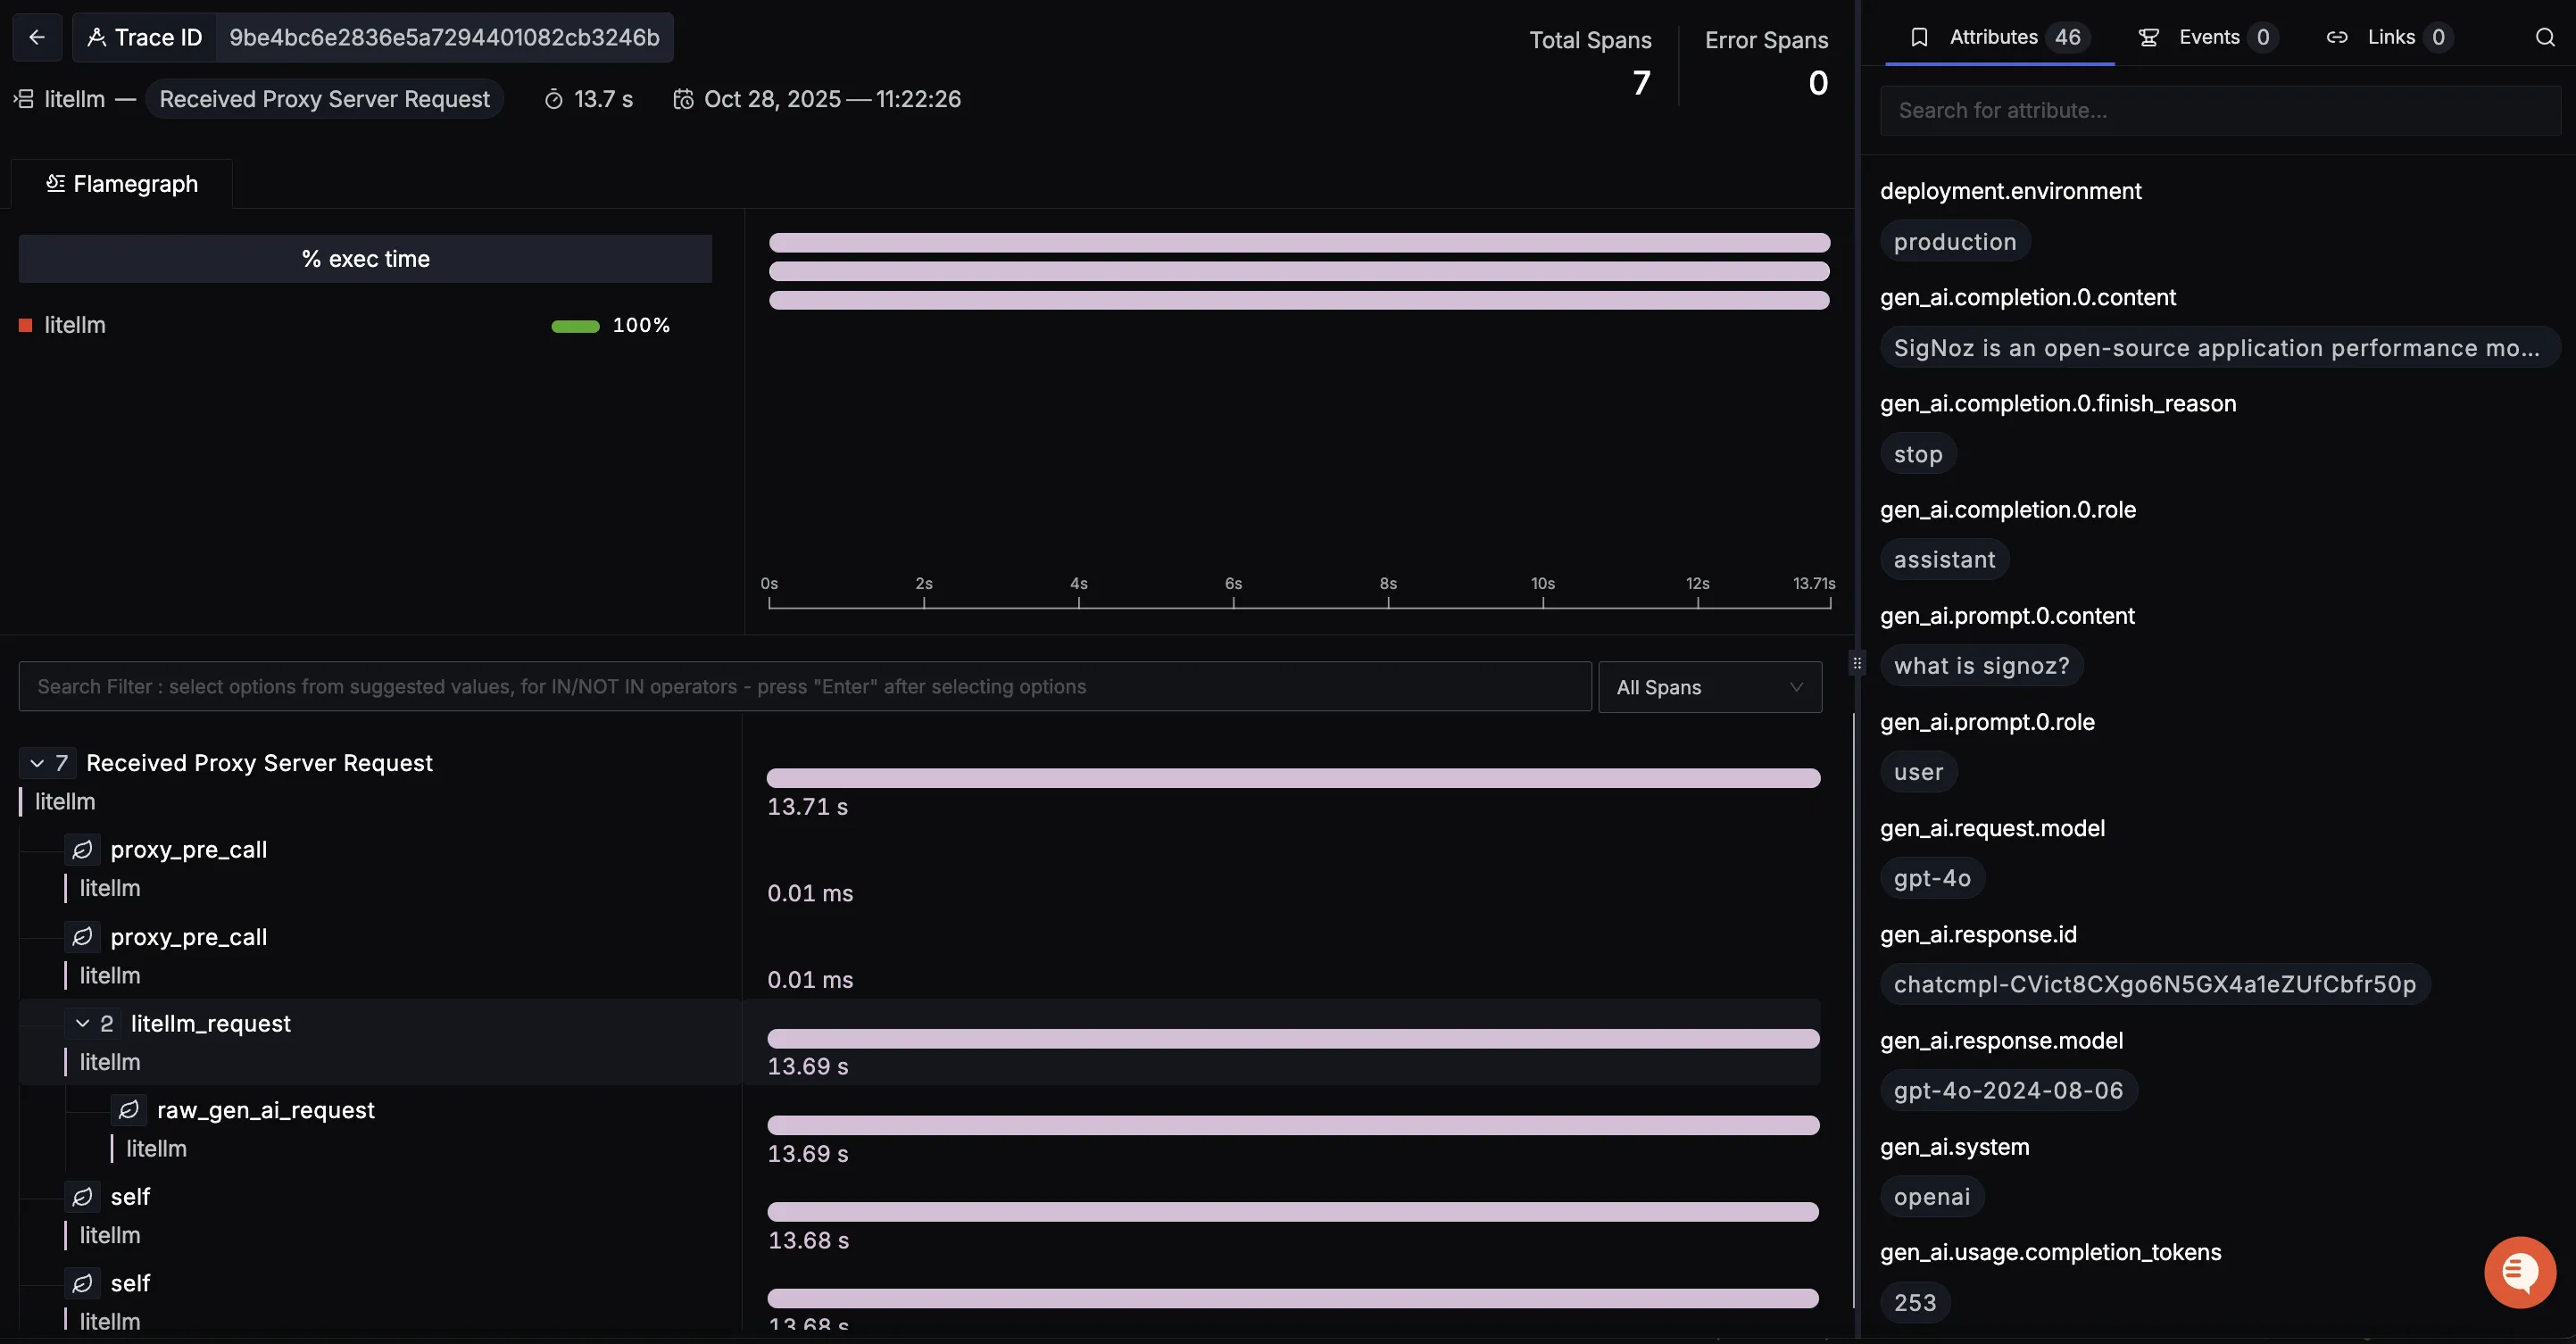
|
||||
|
||||
## Dashboard
|
||||
|
||||
You can also check out our custom LiteLLM Proxy dashboard [here](https://signoz.io/docs/dashboards/dashboard-templates/litellm-proxy-dashboard/) which provides specialized visualizations for monitoring your LiteLLM Proxy usage in applications. The dashboard includes pre-built charts specifically tailored for LLM usage, along with import instructions to get started quickly.
|
||||
|
||||
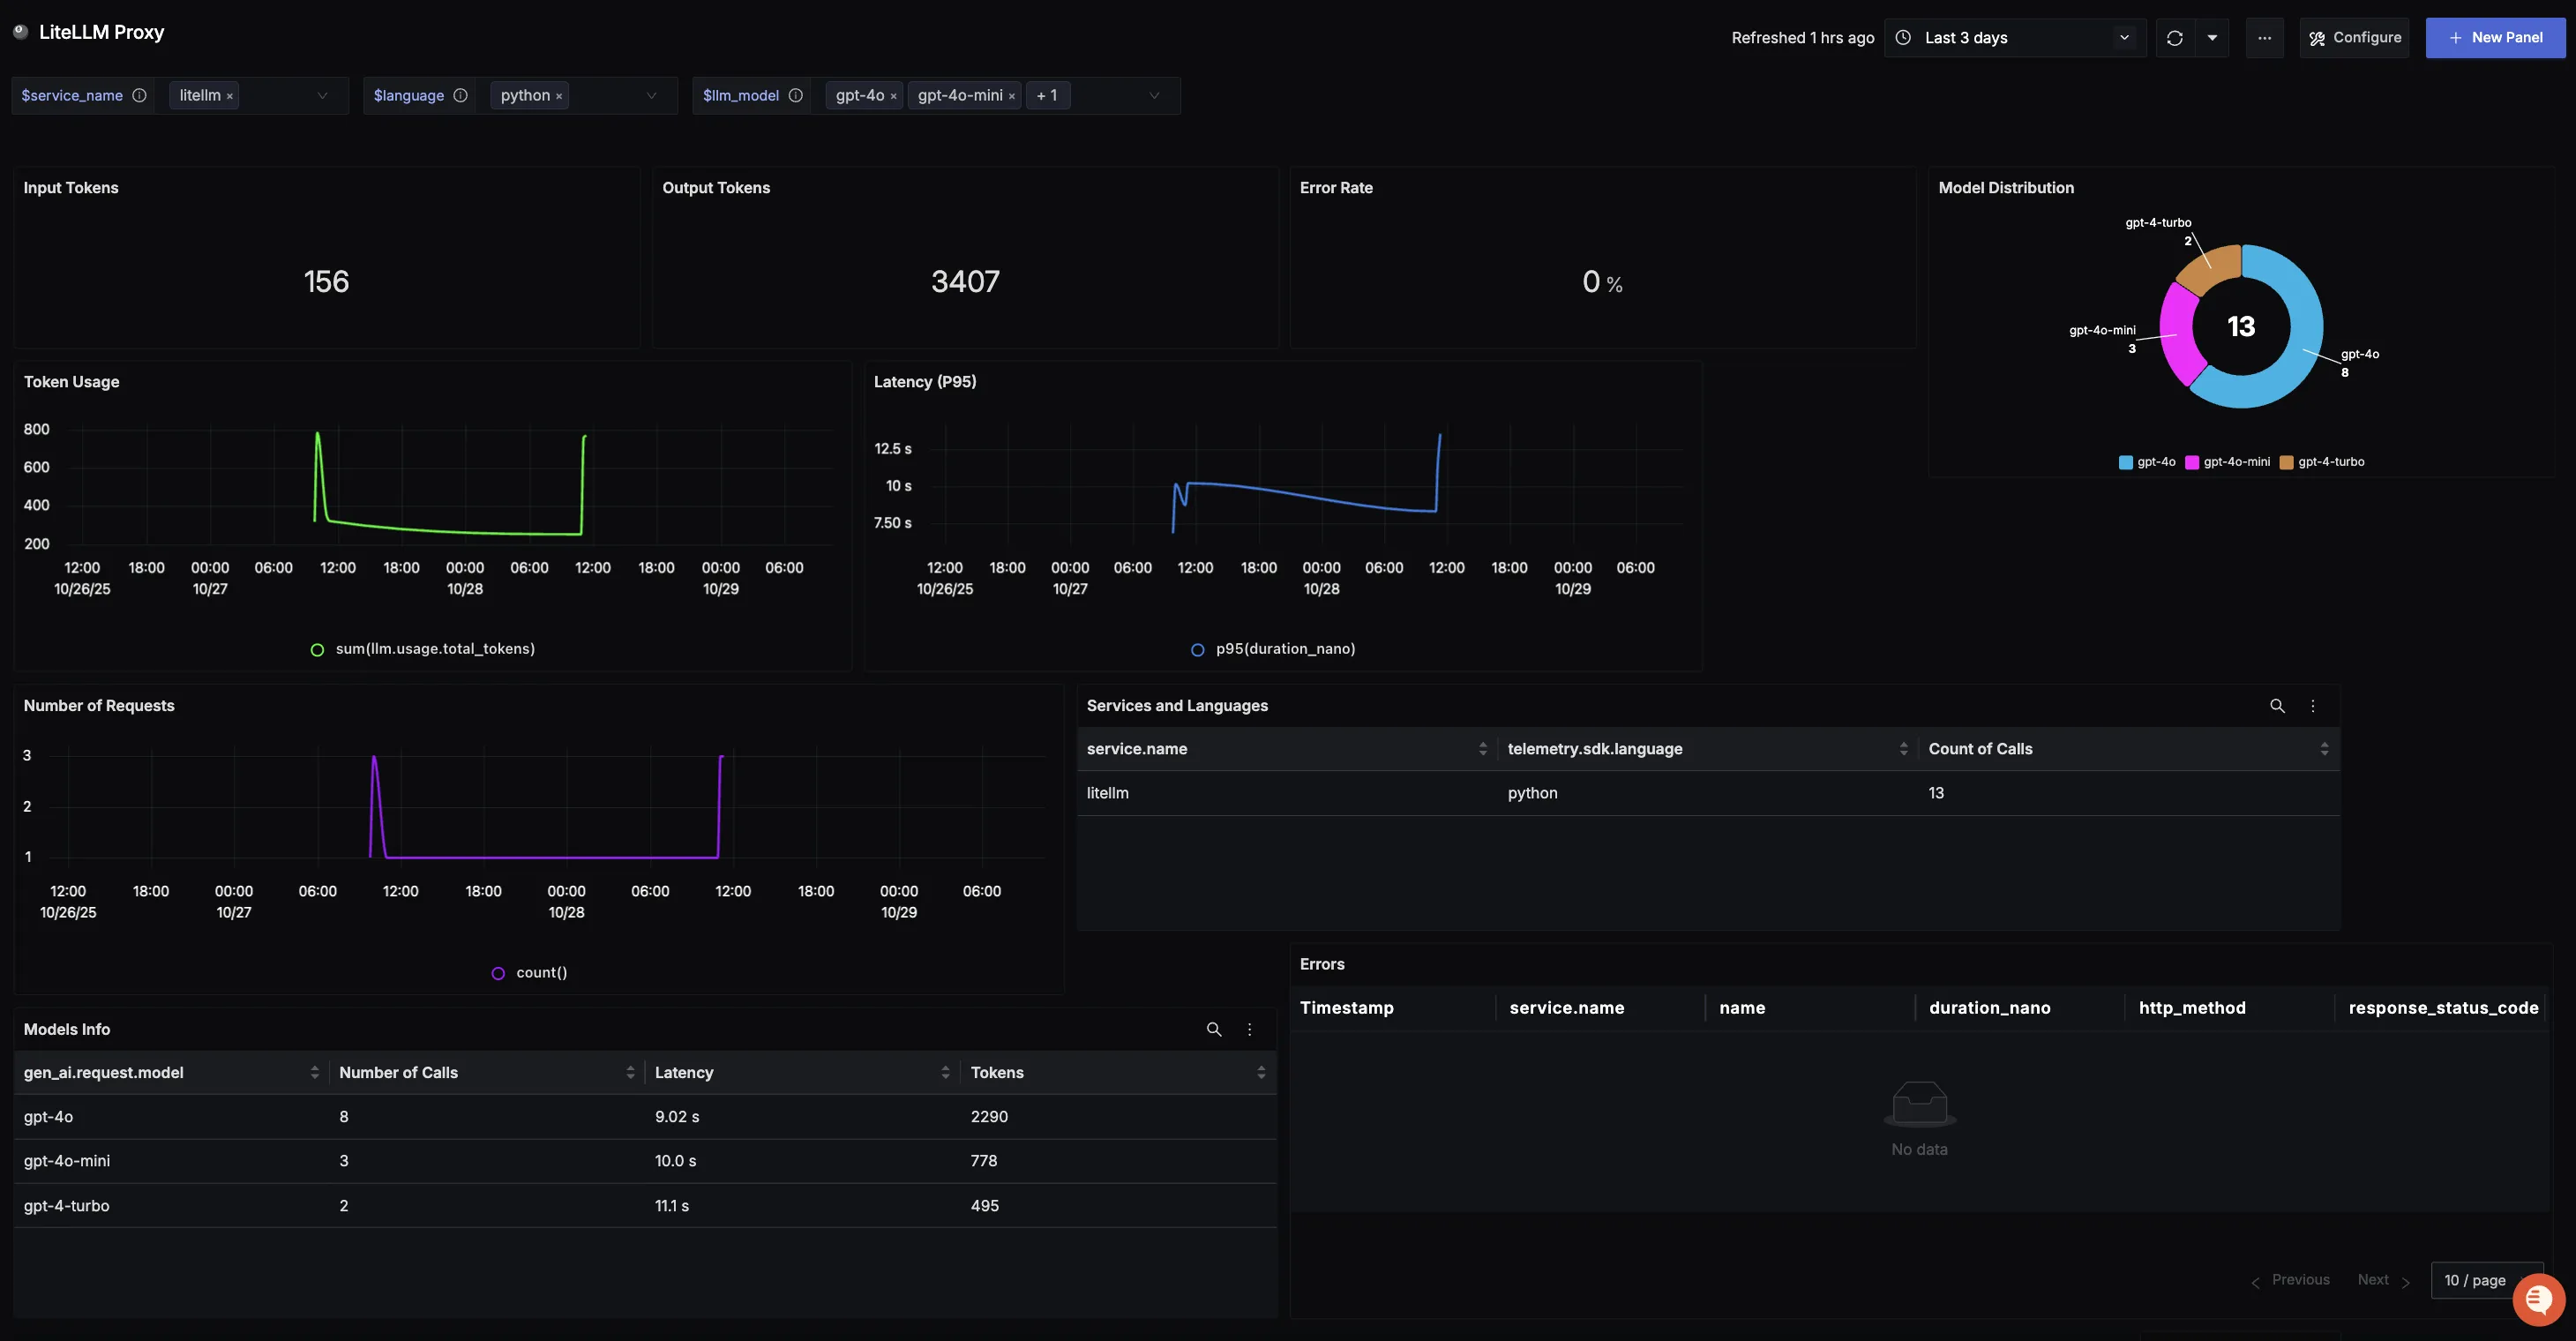
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
|
@ -1,7 +1,7 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Azure AI Image Generation
|
||||
# Azure AI Image Generation (Black Forest Labs - Flux)
|
||||
|
||||
Azure AI provides powerful image generation capabilities using FLUX models from Black Forest Labs to create high-quality images from text descriptions.
|
||||
|
||||
|
|
@ -12,7 +12,7 @@ Azure AI provides powerful image generation capabilities using FLUX models from
|
|||
| Description | Azure AI Image Generation uses FLUX models to generate high-quality images from text descriptions. |
|
||||
| Provider Route on LiteLLM | `azure_ai/` |
|
||||
| Provider Doc | [Azure AI FLUX Models ↗](https://techcommunity.microsoft.com/blog/azure-ai-foundry-blog/black-forest-labs-flux-1-kontext-pro-and-flux1-1-pro-now-available-in-azure-ai-f/4434659) |
|
||||
| Supported Operations | [`/images/generations`](#image-generation) |
|
||||
| Supported Operations | [`/images/generations`](#image-generation), [`/images/edits`](#image-editing) |
|
||||
|
||||
## Setup
|
||||
|
||||
|
|
@ -33,6 +33,7 @@ Get your API key and endpoint from [Azure AI Studio](https://ai.azure.com/).
|
|||
|------------|-------------|----------------|
|
||||
| `azure_ai/FLUX-1.1-pro` | Latest FLUX 1.1 Pro model for high-quality image generation | $0.04 |
|
||||
| `azure_ai/FLUX.1-Kontext-pro` | FLUX 1 Kontext Pro model with enhanced context understanding | $0.04 |
|
||||
| `azure_ai/flux.2-pro` | FLUX 2 Pro model for next-generation image generation | $0.04 |
|
||||
|
||||
## Image Generation
|
||||
|
||||
|
|
@ -85,6 +86,32 @@ print(response.data[0].url)
|
|||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="flux2" label="FLUX 2 Pro">
|
||||
|
||||
```python showLineNumbers title="FLUX 2 Pro Image Generation"
|
||||
import litellm
|
||||
import os
|
||||
|
||||
# Set your API credentials
|
||||
os.environ["AZURE_AI_API_KEY"] = "your-api-key-here"
|
||||
os.environ["AZURE_AI_API_BASE"] = "your-azure-ai-endpoint" # e.g., https://litellm-ci-cd-prod.services.ai.azure.com
|
||||
|
||||
# Generate image with FLUX 2 Pro
|
||||
response = litellm.image_generation(
|
||||
model="azure_ai/flux.2-pro",
|
||||
prompt="A photograph of a red fox in an autumn forest",
|
||||
api_base=os.environ["AZURE_AI_API_BASE"],
|
||||
api_key=os.environ["AZURE_AI_API_KEY"],
|
||||
api_version="preview",
|
||||
size="1024x1024",
|
||||
n=1
|
||||
)
|
||||
|
||||
print(response.data[0].b64_json) # FLUX 2 returns base64 encoded images
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="async" label="Async Usage">
|
||||
|
||||
```python showLineNumbers title="Async Image Generation"
|
||||
|
|
@ -165,6 +192,15 @@ model_list:
|
|||
model_info:
|
||||
mode: image_generation
|
||||
|
||||
- model_name: azure-flux-2-pro
|
||||
litellm_params:
|
||||
model: azure_ai/flux.2-pro
|
||||
api_key: os.environ/AZURE_AI_API_KEY
|
||||
api_base: os.environ/AZURE_AI_API_BASE
|
||||
api_version: preview
|
||||
model_info:
|
||||
mode: image_generation
|
||||
|
||||
general_settings:
|
||||
master_key: sk-1234
|
||||
```
|
||||
|
|
@ -239,6 +275,103 @@ curl --location 'http://localhost:4000/v1/images/generations' \
|
|||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Image Editing
|
||||
|
||||
FLUX 2 Pro supports image editing by passing an input image along with a prompt describing the desired modifications.
|
||||
|
||||
### Usage - LiteLLM Python SDK
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="basic-edit" label="Basic Image Edit">
|
||||
|
||||
```python showLineNumbers title="Basic Image Editing with FLUX 2 Pro"
|
||||
import litellm
|
||||
import os
|
||||
|
||||
# Set your API credentials
|
||||
os.environ["AZURE_AI_API_KEY"] = "your-api-key-here"
|
||||
os.environ["AZURE_AI_API_BASE"] = "your-azure-ai-endpoint" # e.g., https://litellm-ci-cd-prod.services.ai.azure.com
|
||||
|
||||
# Edit an existing image
|
||||
response = litellm.image_edit(
|
||||
model="azure_ai/flux.2-pro",
|
||||
prompt="Add a red hat to the subject",
|
||||
image=open("input_image.png", "rb"),
|
||||
api_base=os.environ["AZURE_AI_API_BASE"],
|
||||
api_key=os.environ["AZURE_AI_API_KEY"],
|
||||
api_version="preview",
|
||||
)
|
||||
|
||||
print(response.data[0].b64_json) # FLUX 2 returns base64 encoded images
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="async-edit" label="Async Image Edit">
|
||||
|
||||
```python showLineNumbers title="Async Image Editing"
|
||||
import litellm
|
||||
import asyncio
|
||||
import os
|
||||
|
||||
async def edit_image():
|
||||
os.environ["AZURE_AI_API_KEY"] = "your-api-key-here"
|
||||
os.environ["AZURE_AI_API_BASE"] = "your-azure-ai-endpoint"
|
||||
|
||||
response = await litellm.aimage_edit(
|
||||
model="azure_ai/flux.2-pro",
|
||||
prompt="Change the background to a sunset beach",
|
||||
image=open("input_image.png", "rb"),
|
||||
api_base=os.environ["AZURE_AI_API_BASE"],
|
||||
api_key=os.environ["AZURE_AI_API_KEY"],
|
||||
api_version="preview",
|
||||
)
|
||||
|
||||
return response
|
||||
|
||||
asyncio.run(edit_image())
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Usage - LiteLLM Proxy Server
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="curl-edit" label="cURL">
|
||||
|
||||
```bash showLineNumbers title="Image Edit via Proxy - cURL"
|
||||
curl --location 'http://localhost:4000/v1/images/edits' \
|
||||
--header 'Authorization: Bearer sk-1234' \
|
||||
--form 'model="azure-flux-2-pro"' \
|
||||
--form 'prompt="Add sunglasses to the person"' \
|
||||
--form 'image=@"input_image.png"'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="openai-sdk-edit" label="OpenAI SDK">
|
||||
|
||||
```python showLineNumbers title="Image Edit via Proxy - OpenAI SDK"
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
base_url="http://localhost:4000",
|
||||
api_key="sk-1234"
|
||||
)
|
||||
|
||||
response = client.images.edit(
|
||||
model="azure-flux-2-pro",
|
||||
prompt="Make the sky more dramatic with storm clouds",
|
||||
image=open("input_image.png", "rb"),
|
||||
)
|
||||
|
||||
print(response.data[0].b64_json)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Supported Parameters
|
||||
|
||||
Azure AI Image Generation supports the following OpenAI-compatible parameters:
|
||||
|
|
|
|||
|
|
@ -498,6 +498,7 @@ router_settings:
|
|||
| DD_VERSION | Version identifier for Datadog logs. Defaults to "unknown"
|
||||
| DEBUG_OTEL | Enable debug mode for OpenTelemetry
|
||||
| DEFAULT_ALLOWED_FAILS | Maximum failures allowed before cooling down a model. Default is 3
|
||||
| DEFAULT_A2A_AGENT_TIMEOUT | Default timeout in seconds for A2A (Agent-to-Agent) protocol requests. Default is 6000
|
||||
| DEFAULT_ANTHROPIC_CHAT_MAX_TOKENS | Default maximum tokens for Anthropic chat completions. Default is 4096
|
||||
| DEFAULT_BATCH_SIZE | Default batch size for operations. Default is 512
|
||||
| DEFAULT_CHUNK_OVERLAP | Default chunk overlap for RAG text splitters. Default is 200
|
||||
|
|
@ -699,6 +700,7 @@ router_settings:
|
|||
| LITELLM_EMAIL | Email associated with LiteLLM account
|
||||
| LITELLM_GLOBAL_MAX_PARALLEL_REQUEST_RETRIES | Maximum retries for parallel requests in LiteLLM
|
||||
| LITELLM_GLOBAL_MAX_PARALLEL_REQUEST_RETRY_TIMEOUT | Timeout for retries of parallel requests in LiteLLM
|
||||
| LITELLM_DISABLE_LAZY_LOADING | When set to "1", "true", "yes", or "on", disables lazy loading of attributes (currently only affects encoding/tiktoken). This ensures encoding is initialized before VCR starts recording HTTP requests, fixing VCR cassette creation issues. See [issue #18659](https://github.com/BerriAI/litellm/issues/18659)
|
||||
| LITELLM_MIGRATION_DIR | Custom migrations directory for prisma migrations, used for baselining db in read-only file systems.
|
||||
| LITELLM_HOSTED_UI | URL of the hosted UI for LiteLLM
|
||||
| LITELLM_UI_API_DOC_BASE_URL | Optional override for the API Reference base URL (used in sample code/docs) when the admin UI runs on a different host than the proxy. Defaults to `PROXY_BASE_URL` when unset.
|
||||
|
|
|
|||
|
|
@ -5,6 +5,12 @@ import TabItem from '@theme/TabItem';
|
|||
|
||||
Use this to loadbalance across Azure + OpenAI.
|
||||
|
||||
Supported Providers:
|
||||
- OpenAI
|
||||
- Azure
|
||||
- Google AI Studio (Gemini)
|
||||
- Vertex AI
|
||||
|
||||
## Proxy Usage
|
||||
|
||||
### Add model to config
|
||||
|
|
|
|||
|
|
@ -420,14 +420,8 @@ const sidebars = {
|
|||
],
|
||||
},
|
||||
"assistants",
|
||||
{
|
||||
type: "category",
|
||||
label: "/audio",
|
||||
items: [
|
||||
"audio_transcription",
|
||||
"text_to_speech",
|
||||
]
|
||||
},
|
||||
"audio_transcription",
|
||||
"text_to_speech",
|
||||
{
|
||||
type: "category",
|
||||
label: "/batches",
|
||||
|
|
@ -477,17 +471,13 @@ const sidebars = {
|
|||
"apply_guardrail",
|
||||
"bedrock_invoke",
|
||||
"interactions",
|
||||
{
|
||||
type: "category",
|
||||
label: "/images",
|
||||
items: [
|
||||
"image_edits",
|
||||
"image_generation",
|
||||
"image_variations",
|
||||
]
|
||||
},
|
||||
"image_edits",
|
||||
"image_generation",
|
||||
"image_variations",
|
||||
"videos",
|
||||
"vector_store_files",
|
||||
"vector_stores/create",
|
||||
"vector_stores/search",
|
||||
{
|
||||
type: "category",
|
||||
label: "/mcp - Model Context Protocol",
|
||||
|
|
@ -531,24 +521,12 @@ const sidebars = {
|
|||
"proxy/pass_through_guardrails"
|
||||
]
|
||||
},
|
||||
{
|
||||
type: "category",
|
||||
label: "/rag",
|
||||
items: [
|
||||
"rag_ingest",
|
||||
"rag_query",
|
||||
]
|
||||
},
|
||||
"rag_ingest",
|
||||
"rag_query",
|
||||
"realtime",
|
||||
"rerank",
|
||||
{
|
||||
type: "category",
|
||||
label: "/responses",
|
||||
items: [
|
||||
"response_api",
|
||||
"response_api_compact",
|
||||
]
|
||||
},
|
||||
"response_api",
|
||||
"response_api_compact",
|
||||
{
|
||||
type: "category",
|
||||
label: "/search",
|
||||
|
|
@ -566,14 +544,7 @@ const sidebars = {
|
|||
]
|
||||
},
|
||||
"skills",
|
||||
{
|
||||
type: "category",
|
||||
label: "/vector_stores",
|
||||
items: [
|
||||
"vector_stores/create",
|
||||
"vector_stores/search",
|
||||
]
|
||||
},
|
||||
|
||||
],
|
||||
},
|
||||
{
|
||||
|
|
|
|||
BIN
flux2_test_image.png
Normal file
BIN
flux2_test_image.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 172 KiB |
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.18-py3-none-any.whl
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.18-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.18.tar.gz
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.18.tar.gz
vendored
Normal file
Binary file not shown.
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "litellm-proxy-extras"
|
||||
version = "0.4.17"
|
||||
version = "0.4.18"
|
||||
description = "Additional files for the LiteLLM Proxy. Reduces the size of the main litellm package."
|
||||
authors = ["BerriAI"]
|
||||
readme = "README.md"
|
||||
|
|
@ -22,7 +22,7 @@ requires = ["poetry-core"]
|
|||
build-backend = "poetry.core.masonry.api"
|
||||
|
||||
[tool.commitizen]
|
||||
version = "0.4.17"
|
||||
version = "0.4.18"
|
||||
version_files = [
|
||||
"pyproject.toml:version",
|
||||
"../requirements.txt:litellm-proxy-extras==",
|
||||
|
|
|
|||
|
|
@ -557,6 +557,8 @@ stability_models: Set = set()
|
|||
github_copilot_models: Set = set()
|
||||
minimax_models: Set = set()
|
||||
aws_polly_models: Set = set()
|
||||
gigachat_models: Set = set()
|
||||
llamagate_models: Set = set()
|
||||
|
||||
|
||||
def is_bedrock_pricing_only_model(key: str) -> bool:
|
||||
|
|
@ -809,6 +811,10 @@ def add_known_models():
|
|||
minimax_models.add(key)
|
||||
elif value.get("litellm_provider") == "aws_polly":
|
||||
aws_polly_models.add(key)
|
||||
elif value.get("litellm_provider") == "gigachat":
|
||||
gigachat_models.add(key)
|
||||
elif value.get("litellm_provider") == "llamagate":
|
||||
llamagate_models.add(key)
|
||||
|
||||
|
||||
add_known_models()
|
||||
|
|
@ -1015,6 +1021,8 @@ models_by_provider: dict = {
|
|||
"github_copilot": github_copilot_models,
|
||||
"minimax": minimax_models,
|
||||
"aws_polly": aws_polly_models,
|
||||
"gigachat": gigachat_models,
|
||||
"llamagate": llamagate_models,
|
||||
}
|
||||
|
||||
# mapping for those models which have larger equivalents
|
||||
|
|
@ -1553,6 +1561,16 @@ if TYPE_CHECKING:
|
|||
# Track if async client cleanup has been registered (for lazy loading)
|
||||
_async_client_cleanup_registered = False
|
||||
|
||||
# Eager loading for backwards compatibility with VCR and other HTTP recording tools
|
||||
# When LITELLM_DISABLE_LAZY_LOADING is set, lazy-loaded attributes are loaded at import time
|
||||
# For now, this only affects encoding (tiktoken) as it was the only reported issue
|
||||
# See: https://github.com/BerriAI/litellm/issues/18659
|
||||
# This ensures encoding is initialized before VCR starts recording HTTP requests
|
||||
if os.getenv("LITELLM_DISABLE_LAZY_LOADING", "").lower() in ("1", "true", "yes", "on"):
|
||||
# Load encoding at import time (pre-#18070 behavior)
|
||||
# This ensures encoding is initialized before VCR starts recording
|
||||
from .main import encoding
|
||||
|
||||
|
||||
def __getattr__(name: str) -> Any:
|
||||
"""Lazy import handler with cached registry for improved performance."""
|
||||
|
|
|
|||
|
|
@ -12,6 +12,7 @@ import litellm
|
|||
from litellm._logging import verbose_logger
|
||||
from litellm.a2a_protocol.streaming_iterator import A2AStreamingIterator
|
||||
from litellm.a2a_protocol.utils import A2ARequestUtils
|
||||
from litellm.constants import DEFAULT_A2A_AGENT_TIMEOUT
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging
|
||||
from litellm.llms.custom_httpx.http_handler import (
|
||||
get_async_httpx_client,
|
||||
|
|
@ -494,7 +495,7 @@ async def create_a2a_client(
|
|||
|
||||
async def aget_agent_card(
|
||||
base_url: str,
|
||||
timeout: float = 60.0,
|
||||
timeout: float = DEFAULT_A2A_AGENT_TIMEOUT,
|
||||
extra_headers: Optional[Dict[str, str]] = None,
|
||||
) -> "AgentCard":
|
||||
"""
|
||||
|
|
|
|||
|
|
@ -278,6 +278,7 @@ MAX_SIZE_PER_ITEM_IN_MEMORY_CACHE_IN_KB = int(
|
|||
DEFAULT_MAX_TOKENS_FOR_TRITON = int(os.getenv("DEFAULT_MAX_TOKENS_FOR_TRITON", 2000))
|
||||
#### Networking settings ####
|
||||
request_timeout: float = float(os.getenv("REQUEST_TIMEOUT", 6000)) # time in seconds
|
||||
DEFAULT_A2A_AGENT_TIMEOUT: float = float(os.getenv("DEFAULT_A2A_AGENT_TIMEOUT", 6000)) # 10 minutes
|
||||
STREAM_SSE_DONE_STRING: str = "[DONE]"
|
||||
STREAM_SSE_DATA_PREFIX: str = "data: "
|
||||
### SPEND TRACKING ###
|
||||
|
|
|
|||
|
|
@ -216,6 +216,8 @@ _generated_endpoints = generate_container_endpoints()
|
|||
# Export generated functions dynamically
|
||||
list_container_files = _generated_endpoints.get("list_container_files")
|
||||
alist_container_files = _generated_endpoints.get("alist_container_files")
|
||||
upload_container_file = _generated_endpoints.get("upload_container_file")
|
||||
aupload_container_file = _generated_endpoints.get("aupload_container_file")
|
||||
retrieve_container_file = _generated_endpoints.get("retrieve_container_file")
|
||||
aretrieve_container_file = _generated_endpoints.get("aretrieve_container_file")
|
||||
delete_container_file = _generated_endpoints.get("delete_container_file")
|
||||
|
|
|
|||
|
|
@ -9,6 +9,16 @@
|
|||
"query_params": ["after", "limit", "order"],
|
||||
"response_type": "ContainerFileListResponse"
|
||||
},
|
||||
{
|
||||
"name": "upload_container_file",
|
||||
"async_name": "aupload_container_file",
|
||||
"path": "/containers/{container_id}/files",
|
||||
"method": "POST",
|
||||
"path_params": ["container_id"],
|
||||
"query_params": [],
|
||||
"response_type": "ContainerFileObject",
|
||||
"is_multipart": true
|
||||
},
|
||||
{
|
||||
"name": "retrieve_container_file",
|
||||
"async_name": "aretrieve_container_file",
|
||||
|
|
|
|||
|
|
@ -13,11 +13,13 @@ from litellm.main import base_llm_http_handler
|
|||
from litellm.types.containers.main import (
|
||||
ContainerCreateOptionalRequestParams,
|
||||
ContainerFileListResponse,
|
||||
ContainerFileObject,
|
||||
ContainerListOptionalRequestParams,
|
||||
ContainerListResponse,
|
||||
ContainerObject,
|
||||
DeleteContainerResult,
|
||||
)
|
||||
from litellm.types.llms.openai import FileTypes
|
||||
from litellm.types.router import GenericLiteLLMParams
|
||||
from litellm.types.utils import CallTypes
|
||||
from litellm.utils import ProviderConfigManager, client
|
||||
|
|
@ -28,11 +30,13 @@ __all__ = [
|
|||
"alist_container_files",
|
||||
"alist_containers",
|
||||
"aretrieve_container",
|
||||
"aupload_container_file",
|
||||
"create_container",
|
||||
"delete_container",
|
||||
"list_container_files",
|
||||
"list_containers",
|
||||
"retrieve_container",
|
||||
"upload_container_file",
|
||||
]
|
||||
|
||||
##### Container Create #######################
|
||||
|
|
@ -1011,3 +1015,236 @@ def list_container_files(
|
|||
extra_kwargs=kwargs,
|
||||
)
|
||||
|
||||
|
||||
##### Container File Upload #######################
|
||||
@client
|
||||
async def aupload_container_file(
|
||||
container_id: str,
|
||||
file: FileTypes,
|
||||
timeout=600, # default to 10 minutes
|
||||
custom_llm_provider: Literal["openai"] = "openai",
|
||||
extra_headers: Optional[Dict[str, Any]] = None,
|
||||
extra_query: Optional[Dict[str, Any]] = None,
|
||||
extra_body: Optional[Dict[str, Any]] = None,
|
||||
**kwargs,
|
||||
) -> ContainerFileObject:
|
||||
"""Asynchronously upload a file to a container.
|
||||
|
||||
This endpoint allows uploading files directly to a container session,
|
||||
supporting various file types like CSV, Excel, Python scripts, etc.
|
||||
|
||||
Parameters:
|
||||
- `container_id` (str): The ID of the container to upload the file to
|
||||
- `file` (FileTypes): The file to upload. Can be:
|
||||
- A tuple of (filename, content, content_type)
|
||||
- A tuple of (filename, content)
|
||||
- A file-like object with read() method
|
||||
- Bytes
|
||||
- A string path to a file
|
||||
- `timeout` (int): Request timeout in seconds
|
||||
- `custom_llm_provider` (Literal["openai"]): The LLM provider to use
|
||||
- `extra_headers` (Optional[Dict[str, Any]]): Additional headers
|
||||
- `extra_query` (Optional[Dict[str, Any]]): Additional query parameters
|
||||
- `extra_body` (Optional[Dict[str, Any]]): Additional body parameters
|
||||
- `kwargs` (dict): Additional keyword arguments
|
||||
|
||||
Returns:
|
||||
- `response` (ContainerFileObject): The uploaded file object
|
||||
|
||||
Example:
|
||||
```python
|
||||
import litellm
|
||||
|
||||
# Upload a CSV file
|
||||
response = await litellm.aupload_container_file(
|
||||
container_id="container_abc123",
|
||||
file=("data.csv", open("data.csv", "rb").read(), "text/csv"),
|
||||
custom_llm_provider="openai",
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
"""
|
||||
local_vars = locals()
|
||||
try:
|
||||
loop = asyncio.get_event_loop()
|
||||
kwargs["async_call"] = True
|
||||
|
||||
func = partial(
|
||||
upload_container_file,
|
||||
container_id=container_id,
|
||||
file=file,
|
||||
timeout=timeout,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
extra_headers=extra_headers,
|
||||
extra_query=extra_query,
|
||||
extra_body=extra_body,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
ctx = contextvars.copy_context()
|
||||
func_with_context = partial(ctx.run, func)
|
||||
init_response = await loop.run_in_executor(None, func_with_context)
|
||||
|
||||
if asyncio.iscoroutine(init_response):
|
||||
response = await init_response
|
||||
else:
|
||||
response = init_response
|
||||
|
||||
return response
|
||||
except Exception as e:
|
||||
raise litellm.exception_type(
|
||||
model="",
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
original_exception=e,
|
||||
completion_kwargs=local_vars,
|
||||
extra_kwargs=kwargs,
|
||||
)
|
||||
|
||||
|
||||
# fmt: off
|
||||
|
||||
@overload
|
||||
def upload_container_file(
|
||||
container_id: str,
|
||||
file: FileTypes,
|
||||
timeout=600,
|
||||
api_key: Optional[str] = None,
|
||||
api_base: Optional[str] = None,
|
||||
api_version: Optional[str] = None,
|
||||
custom_llm_provider: Literal["openai"] = "openai",
|
||||
*,
|
||||
aupload_container_file: Literal[True],
|
||||
**kwargs,
|
||||
) -> Coroutine[Any, Any, ContainerFileObject]:
|
||||
...
|
||||
|
||||
|
||||
@overload
|
||||
def upload_container_file(
|
||||
container_id: str,
|
||||
file: FileTypes,
|
||||
timeout=600,
|
||||
api_key: Optional[str] = None,
|
||||
api_base: Optional[str] = None,
|
||||
api_version: Optional[str] = None,
|
||||
custom_llm_provider: Literal["openai"] = "openai",
|
||||
*,
|
||||
aupload_container_file: Literal[False] = False,
|
||||
**kwargs,
|
||||
) -> ContainerFileObject:
|
||||
...
|
||||
|
||||
# fmt: on
|
||||
|
||||
|
||||
@client
|
||||
def upload_container_file(
|
||||
container_id: str,
|
||||
file: FileTypes,
|
||||
timeout=600, # default to 10 minutes
|
||||
api_key: Optional[str] = None,
|
||||
api_base: Optional[str] = None,
|
||||
api_version: Optional[str] = None,
|
||||
custom_llm_provider: Literal["openai"] = "openai",
|
||||
extra_headers: Optional[Dict[str, Any]] = None,
|
||||
extra_query: Optional[Dict[str, Any]] = None,
|
||||
extra_body: Optional[Dict[str, Any]] = None,
|
||||
**kwargs,
|
||||
) -> Union[
|
||||
ContainerFileObject,
|
||||
Coroutine[Any, Any, ContainerFileObject],
|
||||
]:
|
||||
"""Upload a file to a container using the OpenAI Container API.
|
||||
|
||||
This endpoint allows uploading files directly to a container session,
|
||||
supporting various file types like CSV, Excel, Python scripts, JSON, etc.
|
||||
This is useful when /chat/completions or /responses sends files to the
|
||||
container but the input file type is limited to PDF. This endpoint lets
|
||||
you work with other file types.
|
||||
|
||||
Currently supports OpenAI
|
||||
|
||||
Example:
|
||||
```python
|
||||
import litellm
|
||||
|
||||
# Upload a CSV file
|
||||
response = litellm.upload_container_file(
|
||||
container_id="container_abc123",
|
||||
file=("data.csv", open("data.csv", "rb").read(), "text/csv"),
|
||||
custom_llm_provider="openai",
|
||||
)
|
||||
print(response)
|
||||
|
||||
# Upload a Python script
|
||||
response = litellm.upload_container_file(
|
||||
container_id="container_abc123",
|
||||
file=("script.py", b"print('hello world')", "text/x-python"),
|
||||
custom_llm_provider="openai",
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
"""
|
||||
from litellm.llms.custom_httpx.container_handler import generic_container_handler
|
||||
|
||||
local_vars = locals()
|
||||
try:
|
||||
litellm_logging_obj: LiteLLMLoggingObj = kwargs.pop("litellm_logging_obj") # type: ignore
|
||||
litellm_call_id: Optional[str] = kwargs.get("litellm_call_id")
|
||||
_is_async = kwargs.pop("async_call", False) is True
|
||||
|
||||
# Check for mock response first
|
||||
mock_response = kwargs.get("mock_response")
|
||||
if mock_response is not None:
|
||||
if isinstance(mock_response, str):
|
||||
mock_response = json.loads(mock_response)
|
||||
|
||||
response = ContainerFileObject(**mock_response)
|
||||
return response
|
||||
|
||||
# get llm provider logic
|
||||
litellm_params = GenericLiteLLMParams(**kwargs)
|
||||
# get provider config
|
||||
container_provider_config: Optional[BaseContainerConfig] = (
|
||||
ProviderConfigManager.get_provider_container_config(
|
||||
provider=litellm.LlmProviders(custom_llm_provider),
|
||||
)
|
||||
)
|
||||
|
||||
if container_provider_config is None:
|
||||
raise ValueError(f"Container provider config not found for provider: {custom_llm_provider}")
|
||||
|
||||
# Pre Call logging
|
||||
litellm_logging_obj.update_environment_variables(
|
||||
model="",
|
||||
optional_params={"container_id": container_id},
|
||||
litellm_params={
|
||||
"litellm_call_id": litellm_call_id,
|
||||
},
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
)
|
||||
|
||||
# Set the correct call type
|
||||
litellm_logging_obj.call_type = CallTypes.upload_container_file.value
|
||||
|
||||
return generic_container_handler.handle(
|
||||
endpoint_name="upload_container_file",
|
||||
container_provider_config=container_provider_config,
|
||||
litellm_params=litellm_params,
|
||||
logging_obj=litellm_logging_obj,
|
||||
extra_headers=extra_headers,
|
||||
extra_query=extra_query,
|
||||
timeout=timeout or DEFAULT_REQUEST_TIMEOUT,
|
||||
_is_async=_is_async,
|
||||
container_id=container_id,
|
||||
file=file,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
raise litellm.exception_type(
|
||||
model="",
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
original_exception=e,
|
||||
completion_kwargs=local_vars,
|
||||
extra_kwargs=kwargs,
|
||||
)
|
||||
|
|
|
|||
|
|
@ -51,6 +51,7 @@ class ArizeLogger(OpenTelemetry):
|
|||
space_id = os.environ.get("ARIZE_SPACE_ID")
|
||||
space_key = os.environ.get("ARIZE_SPACE_KEY")
|
||||
api_key = os.environ.get("ARIZE_API_KEY")
|
||||
project_name = os.environ.get("ARIZE_PROJECT_NAME")
|
||||
|
||||
grpc_endpoint = os.environ.get("ARIZE_ENDPOINT")
|
||||
http_endpoint = os.environ.get("ARIZE_HTTP_ENDPOINT")
|
||||
|
|
@ -74,6 +75,7 @@ class ArizeLogger(OpenTelemetry):
|
|||
api_key=api_key,
|
||||
protocol=protocol,
|
||||
endpoint=endpoint,
|
||||
project_name=project_name,
|
||||
)
|
||||
|
||||
async def async_service_success_hook(
|
||||
|
|
|
|||
|
|
@ -54,38 +54,6 @@ RAW_REQUEST_SPAN_NAME = "raw_gen_ai_request"
|
|||
LITELLM_REQUEST_SPAN_NAME = "litellm_request"
|
||||
|
||||
|
||||
def _get_litellm_resource():
|
||||
"""
|
||||
Create a proper OpenTelemetry Resource that respects OTEL_RESOURCE_ATTRIBUTES
|
||||
while maintaining backward compatibility with LiteLLM-specific environment variables.
|
||||
"""
|
||||
from opentelemetry.sdk.resources import OTELResourceDetector, Resource
|
||||
|
||||
# Create base resource attributes with LiteLLM-specific defaults
|
||||
# These will be overridden by OTEL_RESOURCE_ATTRIBUTES if present
|
||||
base_attributes: Dict[str, Optional[str]] = {
|
||||
"service.name": os.getenv("OTEL_SERVICE_NAME", "litellm"),
|
||||
"deployment.environment": os.getenv("OTEL_ENVIRONMENT_NAME", "production"),
|
||||
# Fix the model_id to use proper environment variable or default to service name
|
||||
"model_id": os.getenv(
|
||||
"OTEL_MODEL_ID", os.getenv("OTEL_SERVICE_NAME", "litellm")
|
||||
),
|
||||
}
|
||||
|
||||
# Create base resource with LiteLLM-specific defaults
|
||||
base_resource = Resource.create(base_attributes) # type: ignore
|
||||
|
||||
# Create resource from OTEL_RESOURCE_ATTRIBUTES using the detector
|
||||
otel_resource_detector = OTELResourceDetector()
|
||||
env_resource = otel_resource_detector.detect()
|
||||
|
||||
# Merge the resources: env_resource takes precedence over base_resource
|
||||
# This ensures OTEL_RESOURCE_ATTRIBUTES overrides LiteLLM defaults
|
||||
merged_resource = base_resource.merge(env_resource)
|
||||
|
||||
return merged_resource
|
||||
|
||||
|
||||
@dataclass
|
||||
class OpenTelemetryConfig:
|
||||
exporter: Union[str, SpanExporter] = "console"
|
||||
|
|
@ -93,6 +61,19 @@ class OpenTelemetryConfig:
|
|||
headers: Optional[str] = None
|
||||
enable_metrics: bool = False
|
||||
enable_events: bool = False
|
||||
service_name: Optional[str] = None
|
||||
deployment_environment: Optional[str] = None
|
||||
model_id: Optional[str] = None
|
||||
|
||||
def __post_init__(self) -> None:
|
||||
if not self.service_name:
|
||||
self.service_name = os.getenv("OTEL_SERVICE_NAME", "litellm")
|
||||
if not self.deployment_environment:
|
||||
self.deployment_environment = os.getenv(
|
||||
"OTEL_ENVIRONMENT_NAME", "production"
|
||||
)
|
||||
if not self.model_id:
|
||||
self.model_id = os.getenv("OTEL_MODEL_ID", self.service_name)
|
||||
|
||||
@classmethod
|
||||
def from_env(cls):
|
||||
|
|
@ -122,6 +103,9 @@ class OpenTelemetryConfig:
|
|||
os.getenv("LITELLM_OTEL_INTEGRATION_ENABLE_EVENTS", "false").lower()
|
||||
== "true"
|
||||
)
|
||||
service_name = os.getenv("OTEL_SERVICE_NAME", "litellm")
|
||||
deployment_environment = os.getenv("OTEL_ENVIRONMENT_NAME", "production")
|
||||
model_id = os.getenv("OTEL_MODEL_ID", service_name)
|
||||
|
||||
if exporter == "in_memory":
|
||||
return cls(exporter=InMemorySpanExporter())
|
||||
|
|
@ -131,6 +115,9 @@ class OpenTelemetryConfig:
|
|||
headers=headers, # example: OTEL_HEADERS=x-honeycomb-team=B85YgLm96***"
|
||||
enable_metrics=enable_metrics,
|
||||
enable_events=enable_events,
|
||||
service_name=service_name,
|
||||
deployment_environment=deployment_environment,
|
||||
model_id=model_id,
|
||||
)
|
||||
|
||||
|
||||
|
|
@ -174,6 +161,22 @@ class OpenTelemetry(CustomLogger):
|
|||
self._init_logs(logger_provider)
|
||||
self._init_otel_logger_on_litellm_proxy()
|
||||
|
||||
@staticmethod
|
||||
def _get_litellm_resource(config: OpenTelemetryConfig):
|
||||
"""Create an OpenTelemetry Resource using config-driven defaults."""
|
||||
from opentelemetry.sdk.resources import OTELResourceDetector, Resource
|
||||
|
||||
base_attributes: Dict[str, Optional[str]] = {
|
||||
"service.name": config.service_name,
|
||||
"deployment.environment": config.deployment_environment,
|
||||
"model_id": config.model_id or config.service_name,
|
||||
}
|
||||
|
||||
base_resource = Resource.create(base_attributes) # type: ignore[arg-type]
|
||||
otel_resource_detector = OTELResourceDetector()
|
||||
env_resource = otel_resource_detector.detect()
|
||||
return base_resource.merge(env_resource)
|
||||
|
||||
def _init_otel_logger_on_litellm_proxy(self):
|
||||
"""
|
||||
Initializes OpenTelemetry for litellm proxy server
|
||||
|
|
@ -266,7 +269,7 @@ class OpenTelemetry(CustomLogger):
|
|||
from opentelemetry.trace import SpanKind
|
||||
|
||||
def create_tracer_provider():
|
||||
provider = TracerProvider(resource=_get_litellm_resource())
|
||||
provider = TracerProvider(resource=self._get_litellm_resource(self.config))
|
||||
provider.add_span_processor(self._get_span_processor())
|
||||
return provider
|
||||
|
||||
|
|
@ -300,7 +303,8 @@ class OpenTelemetry(CustomLogger):
|
|||
def create_meter_provider():
|
||||
metric_reader = self._get_metric_reader()
|
||||
return MeterProvider(
|
||||
metric_readers=[metric_reader], resource=_get_litellm_resource()
|
||||
metric_readers=[metric_reader],
|
||||
resource=self._get_litellm_resource(self.config),
|
||||
)
|
||||
|
||||
meter_provider = self._get_or_create_provider(
|
||||
|
|
@ -355,7 +359,9 @@ class OpenTelemetry(CustomLogger):
|
|||
from opentelemetry.sdk._logs.export import BatchLogRecordProcessor
|
||||
|
||||
def create_logger_provider():
|
||||
provider = OTLoggerProvider(resource=_get_litellm_resource())
|
||||
provider = OTLoggerProvider(
|
||||
resource=self._get_litellm_resource(self.config)
|
||||
)
|
||||
log_exporter = self._get_log_exporter()
|
||||
provider.add_log_record_processor(
|
||||
BatchLogRecordProcessor(log_exporter) # type: ignore[arg-type]
|
||||
|
|
@ -606,7 +612,7 @@ class OpenTelemetry(CustomLogger):
|
|||
from opentelemetry.sdk.trace import TracerProvider
|
||||
|
||||
# Create a temporary tracer provider with dynamic headers
|
||||
temp_provider = TracerProvider(resource=_get_litellm_resource())
|
||||
temp_provider = TracerProvider(resource=self._get_litellm_resource(self.config))
|
||||
temp_provider.add_span_processor(
|
||||
self._get_span_processor(dynamic_headers=dynamic_headers)
|
||||
)
|
||||
|
|
@ -987,9 +993,9 @@ class OpenTelemetry(CustomLogger):
|
|||
|
||||
# Get the resource from the logger provider
|
||||
logger_provider = get_logger_provider()
|
||||
resource = (
|
||||
getattr(logger_provider, "_resource", None) or _get_litellm_resource()
|
||||
)
|
||||
resource = getattr(
|
||||
logger_provider, "_resource", None
|
||||
) or self._get_litellm_resource(self.config)
|
||||
|
||||
parent_ctx = span.get_span_context()
|
||||
provider = (kwargs.get("litellm_params") or {}).get(
|
||||
|
|
@ -1910,7 +1916,9 @@ class OpenTelemetry(CustomLogger):
|
|||
)
|
||||
|
||||
_split_otel_headers = OpenTelemetry._get_headers_dictionary(self.OTEL_HEADERS)
|
||||
normalized_endpoint = self._normalize_otel_endpoint(self.OTEL_ENDPOINT, "metrics")
|
||||
normalized_endpoint = self._normalize_otel_endpoint(
|
||||
self.OTEL_ENDPOINT, "metrics"
|
||||
)
|
||||
|
||||
if self.OTEL_EXPORTER == "console":
|
||||
exporter = ConsoleMetricExporter()
|
||||
|
|
|
|||
|
|
@ -3630,6 +3630,7 @@ def _init_custom_logger_compatible_class( # noqa: PLR0915
|
|||
otel_config = OpenTelemetryConfig(
|
||||
exporter=arize_config.protocol,
|
||||
endpoint=arize_config.endpoint,
|
||||
service_name=arize_config.project_name,
|
||||
)
|
||||
|
||||
os.environ[
|
||||
|
|
|
|||
|
|
@ -990,6 +990,10 @@ class AzureChatCompletion(BaseAzureLLM, BaseLLM):
|
|||
def create_azure_base_url(
|
||||
self, azure_client_params: dict, model: Optional[str]
|
||||
) -> str:
|
||||
from litellm.llms.azure_ai.image_generation import (
|
||||
AzureFoundryFluxImageGenerationConfig,
|
||||
)
|
||||
|
||||
api_base: str = azure_client_params.get(
|
||||
"azure_endpoint", ""
|
||||
) # "https://example-endpoint.openai.azure.com"
|
||||
|
|
@ -999,6 +1003,15 @@ class AzureChatCompletion(BaseAzureLLM, BaseLLM):
|
|||
if model is None:
|
||||
model = ""
|
||||
|
||||
# Handle FLUX 2 models on Azure AI which use a different URL pattern
|
||||
# e.g., /providers/blackforestlabs/v1/flux-2-pro instead of /openai/deployments/{model}/images/generations
|
||||
if AzureFoundryFluxImageGenerationConfig.is_flux2_model(model):
|
||||
return AzureFoundryFluxImageGenerationConfig.get_flux2_image_generation_url(
|
||||
api_base=api_base,
|
||||
model=model,
|
||||
api_version=api_version,
|
||||
)
|
||||
|
||||
if "/openai/deployments/" in api_base:
|
||||
base_url_with_deployment = api_base
|
||||
else:
|
||||
|
|
|
|||
|
|
@ -1,15 +1,28 @@
|
|||
from litellm.llms.azure_ai.image_generation.flux_transformation import (
|
||||
AzureFoundryFluxImageGenerationConfig,
|
||||
)
|
||||
from litellm.llms.base_llm.image_edit.transformation import BaseImageEditConfig
|
||||
|
||||
from .flux2_transformation import AzureFoundryFlux2ImageEditConfig
|
||||
from .transformation import AzureFoundryFluxImageEditConfig
|
||||
|
||||
__all__ = ["AzureFoundryFluxImageEditConfig"]
|
||||
__all__ = ["AzureFoundryFluxImageEditConfig", "AzureFoundryFlux2ImageEditConfig"]
|
||||
|
||||
|
||||
def get_azure_ai_image_edit_config(model: str) -> BaseImageEditConfig:
|
||||
model = model.lower()
|
||||
model = model.replace("-", "")
|
||||
model = model.replace("_", "")
|
||||
if model == "" or "flux" in model: # empty model is flux
|
||||
"""
|
||||
Get the appropriate image edit config for an Azure AI model.
|
||||
|
||||
- FLUX 2 models use JSON with base64 image
|
||||
- FLUX 1 models use multipart/form-data
|
||||
"""
|
||||
# Check if it's a FLUX 2 model
|
||||
if AzureFoundryFluxImageGenerationConfig.is_flux2_model(model):
|
||||
return AzureFoundryFlux2ImageEditConfig()
|
||||
|
||||
# Default to FLUX 1 config for other FLUX models
|
||||
model_normalized = model.lower().replace("-", "").replace("_", "")
|
||||
if model_normalized == "" or "flux" in model_normalized:
|
||||
return AzureFoundryFluxImageEditConfig()
|
||||
else:
|
||||
raise ValueError(f"Model {model} is not supported for Azure AI image editing.")
|
||||
|
||||
raise ValueError(f"Model {model} is not supported for Azure AI image editing.")
|
||||
|
|
|
|||
167
litellm/llms/azure_ai/image_edit/flux2_transformation.py
Normal file
167
litellm/llms/azure_ai/image_edit/flux2_transformation.py
Normal file
|
|
@ -0,0 +1,167 @@
|
|||
import base64
|
||||
from io import BufferedReader
|
||||
from typing import Any, Dict, Optional, Tuple
|
||||
|
||||
from httpx._types import RequestFiles
|
||||
|
||||
import litellm
|
||||
from litellm.llms.azure_ai.common_utils import AzureFoundryModelInfo
|
||||
from litellm.llms.azure_ai.image_generation.flux_transformation import (
|
||||
AzureFoundryFluxImageGenerationConfig,
|
||||
)
|
||||
from litellm.llms.openai.image_edit.transformation import OpenAIImageEditConfig
|
||||
from litellm.secret_managers.main import get_secret_str
|
||||
from litellm.types.images.main import ImageEditOptionalRequestParams
|
||||
from litellm.types.llms.openai import FileTypes
|
||||
from litellm.types.router import GenericLiteLLMParams
|
||||
|
||||
|
||||
class AzureFoundryFlux2ImageEditConfig(OpenAIImageEditConfig):
|
||||
"""
|
||||
Azure AI Foundry FLUX 2 image edit config
|
||||
|
||||
Supports FLUX 2 models (e.g., flux.2-pro) for image editing.
|
||||
Uses the same /providers/blackforestlabs/v1/flux-2-pro endpoint as image generation,
|
||||
with the image passed as base64 in JSON body.
|
||||
"""
|
||||
|
||||
def get_supported_openai_params(self, model: str) -> list:
|
||||
"""
|
||||
FLUX 2 supports a subset of OpenAI image edit params
|
||||
"""
|
||||
return [
|
||||
"prompt",
|
||||
"image",
|
||||
"model",
|
||||
"n",
|
||||
"size",
|
||||
]
|
||||
|
||||
def map_openai_params(
|
||||
self,
|
||||
image_edit_optional_params: ImageEditOptionalRequestParams,
|
||||
model: str,
|
||||
drop_params: bool,
|
||||
) -> Dict:
|
||||
"""
|
||||
Map OpenAI params to FLUX 2 params.
|
||||
FLUX 2 uses the same param names as OpenAI for supported params.
|
||||
"""
|
||||
mapped_params: Dict[str, Any] = {}
|
||||
supported_params = self.get_supported_openai_params(model)
|
||||
|
||||
for key, value in dict(image_edit_optional_params).items():
|
||||
if key in supported_params and value is not None:
|
||||
mapped_params[key] = value
|
||||
|
||||
return mapped_params
|
||||
|
||||
def use_multipart_form_data(self) -> bool:
|
||||
"""FLUX 2 uses JSON requests, not multipart/form-data."""
|
||||
return False
|
||||
|
||||
def validate_environment(
|
||||
self,
|
||||
headers: dict,
|
||||
model: str,
|
||||
api_key: Optional[str] = None,
|
||||
) -> dict:
|
||||
"""
|
||||
Validate Azure AI Foundry environment and set up authentication
|
||||
"""
|
||||
api_key = AzureFoundryModelInfo.get_api_key(api_key)
|
||||
|
||||
if not api_key:
|
||||
raise ValueError(
|
||||
f"Azure AI API key is required for model {model}. Set AZURE_AI_API_KEY environment variable or pass api_key parameter."
|
||||
)
|
||||
|
||||
headers.update(
|
||||
{
|
||||
"Api-Key": api_key,
|
||||
"Content-Type": "application/json",
|
||||
}
|
||||
)
|
||||
return headers
|
||||
|
||||
def transform_image_edit_request(
|
||||
self,
|
||||
model: str,
|
||||
prompt: str,
|
||||
image: FileTypes,
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
headers: dict,
|
||||
) -> Tuple[Dict, RequestFiles]:
|
||||
"""
|
||||
Transform image edit request for FLUX 2.
|
||||
|
||||
FLUX 2 uses the same endpoint for generation and editing,
|
||||
with the image passed as base64 in the JSON body.
|
||||
"""
|
||||
image_b64 = self._convert_image_to_base64(image)
|
||||
|
||||
# Build request body with required params
|
||||
request_body: Dict[str, Any] = {
|
||||
"prompt": prompt,
|
||||
"image": image_b64,
|
||||
"model": model,
|
||||
}
|
||||
|
||||
# Add mapped optional params (already filtered by map_openai_params)
|
||||
request_body.update(image_edit_optional_request_params)
|
||||
|
||||
# Return JSON body and empty files list (FLUX 2 doesn't use multipart)
|
||||
return request_body, []
|
||||
|
||||
def _convert_image_to_base64(self, image: Any) -> str:
|
||||
"""Convert image file to base64 string"""
|
||||
# Handle list of images (take first one)
|
||||
if isinstance(image, list):
|
||||
if len(image) == 0:
|
||||
raise ValueError("Empty image list provided")
|
||||
image = image[0]
|
||||
|
||||
if isinstance(image, BufferedReader):
|
||||
image_bytes = image.read()
|
||||
image.seek(0) # Reset file pointer for potential reuse
|
||||
elif isinstance(image, bytes):
|
||||
image_bytes = image
|
||||
elif hasattr(image, "read"):
|
||||
image_bytes = image.read() # type: ignore
|
||||
else:
|
||||
raise ValueError(f"Unsupported image type: {type(image)}")
|
||||
|
||||
return base64.b64encode(image_bytes).decode("utf-8")
|
||||
|
||||
def get_complete_url(
|
||||
self,
|
||||
model: str,
|
||||
api_base: Optional[str],
|
||||
litellm_params: dict,
|
||||
) -> str:
|
||||
"""
|
||||
Constructs a complete URL for Azure AI Foundry FLUX 2 image edits.
|
||||
|
||||
Uses the same /providers/blackforestlabs/v1/flux-2-pro endpoint as image generation.
|
||||
"""
|
||||
api_base = AzureFoundryModelInfo.get_api_base(api_base)
|
||||
|
||||
if api_base is None:
|
||||
raise ValueError(
|
||||
"Azure AI API base is required. Set AZURE_AI_API_BASE environment variable or pass api_base parameter."
|
||||
)
|
||||
|
||||
api_version = (
|
||||
litellm_params.get("api_version")
|
||||
or litellm.api_version
|
||||
or get_secret_str("AZURE_AI_API_VERSION")
|
||||
or "preview"
|
||||
)
|
||||
|
||||
return AzureFoundryFluxImageGenerationConfig.get_flux2_image_generation_url(
|
||||
api_base=api_base,
|
||||
model=model,
|
||||
api_version=api_version,
|
||||
)
|
||||
|
||||
|
|
@ -71,9 +71,11 @@ class AzureFoundryFluxImageEditConfig(OpenAIImageEditConfig):
|
|||
"Azure AI API base is required. Set AZURE_AI_API_BASE environment variable or pass api_base parameter."
|
||||
)
|
||||
|
||||
api_version = (litellm_params.get("api_version") or litellm.api_version
|
||||
or get_secret_str("AZURE_AI_API_VERSION")
|
||||
)
|
||||
api_version = (
|
||||
litellm_params.get("api_version")
|
||||
or litellm.api_version
|
||||
or get_secret_str("AZURE_AI_API_VERSION")
|
||||
)
|
||||
if api_version is None:
|
||||
# API version is mandatory for Azure AI Foundry
|
||||
raise ValueError(
|
||||
|
|
|
|||
|
|
@ -1,3 +1,5 @@
|
|||
from typing import Optional
|
||||
|
||||
from litellm.llms.openai.image_generation import GPTImageGenerationConfig
|
||||
|
||||
|
||||
|
|
@ -11,4 +13,56 @@ class AzureFoundryFluxImageGenerationConfig(GPTImageGenerationConfig):
|
|||
|
||||
From our test suite - following GPTImageGenerationConfig is working for this model
|
||||
"""
|
||||
pass
|
||||
|
||||
@staticmethod
|
||||
def get_flux2_image_generation_url(
|
||||
api_base: Optional[str],
|
||||
model: str,
|
||||
api_version: Optional[str],
|
||||
) -> str:
|
||||
"""
|
||||
Constructs the complete URL for Azure AI FLUX 2 image generation.
|
||||
|
||||
FLUX 2 models on Azure AI use a different URL pattern than standard Azure OpenAI:
|
||||
- Standard: /openai/deployments/{model}/images/generations
|
||||
- FLUX 2: /providers/blackforestlabs/v1/flux-2-pro
|
||||
|
||||
Args:
|
||||
api_base: Base URL (e.g., https://litellm-ci-cd-prod.services.ai.azure.com)
|
||||
model: Model name (e.g., flux.2-pro)
|
||||
api_version: API version (e.g., preview)
|
||||
|
||||
Returns:
|
||||
Complete URL for the FLUX 2 image generation endpoint
|
||||
"""
|
||||
if api_base is None:
|
||||
raise ValueError(
|
||||
"api_base is required for Azure AI FLUX 2 image generation"
|
||||
)
|
||||
|
||||
api_base = api_base.rstrip("/")
|
||||
api_version = api_version or "preview"
|
||||
|
||||
# If the api_base already contains /providers/, it's already a complete path
|
||||
if "/providers/" in api_base:
|
||||
if "?" in api_base:
|
||||
return api_base
|
||||
return f"{api_base}?api-version={api_version}"
|
||||
|
||||
# Construct the FLUX 2 provider path
|
||||
# Model name flux.2-pro maps to endpoint flux-2-pro
|
||||
return f"{api_base}/providers/blackforestlabs/v1/flux-2-pro?api-version={api_version}"
|
||||
|
||||
@staticmethod
|
||||
def is_flux2_model(model: str) -> bool:
|
||||
"""
|
||||
Check if the model is an Azure AI FLUX 2 model.
|
||||
|
||||
Args:
|
||||
model: Model name (e.g., flux.2-pro, azure_ai/flux.2-pro)
|
||||
|
||||
Returns:
|
||||
True if the model is a FLUX 2 model
|
||||
"""
|
||||
model_lower = model.lower().replace(".", "-").replace("_", "-")
|
||||
return "flux-2" in model_lower or "flux2" in model_lower
|
||||
|
|
|
|||
|
|
@ -88,6 +88,34 @@ def _build_query_params(
|
|||
return params
|
||||
|
||||
|
||||
def _prepare_multipart_file_upload(
|
||||
file: Any,
|
||||
headers: Dict[str, Any],
|
||||
) -> tuple:
|
||||
"""
|
||||
Prepare file and headers for multipart upload.
|
||||
|
||||
Returns:
|
||||
Tuple of (files_dict, headers_without_content_type)
|
||||
"""
|
||||
from litellm.litellm_core_utils.prompt_templates.common_utils import (
|
||||
extract_file_data,
|
||||
)
|
||||
|
||||
extracted = extract_file_data(file)
|
||||
filename = extracted.get("filename") or "file"
|
||||
content = extracted.get("content") or b""
|
||||
content_type = extracted.get("content_type") or "application/octet-stream"
|
||||
files = {"file": (filename, content, content_type)}
|
||||
|
||||
# Remove content-type header - httpx will set it automatically for multipart
|
||||
headers_copy = headers.copy()
|
||||
headers_copy.pop("content-type", None)
|
||||
headers_copy.pop("Content-Type", None)
|
||||
|
||||
return files, headers_copy
|
||||
|
||||
|
||||
class GenericContainerHandler:
|
||||
"""
|
||||
Generic handler for container file API endpoints.
|
||||
|
|
@ -210,6 +238,7 @@ class GenericContainerHandler:
|
|||
# Make request
|
||||
method = endpoint_config["method"].upper()
|
||||
returns_binary = endpoint_config.get("returns_binary", False)
|
||||
is_multipart = endpoint_config.get("is_multipart", False)
|
||||
|
||||
try:
|
||||
if method == "GET":
|
||||
|
|
@ -217,7 +246,11 @@ class GenericContainerHandler:
|
|||
elif method == "DELETE":
|
||||
response = http_client.delete(url=url, headers=headers, params=query_params)
|
||||
elif method == "POST":
|
||||
response = http_client.post(url=url, headers=headers, params=query_params)
|
||||
if is_multipart and "file" in kwargs:
|
||||
files, headers = _prepare_multipart_file_upload(kwargs["file"], headers)
|
||||
response = http_client.post(url=url, headers=headers, params=query_params, files=files)
|
||||
else:
|
||||
response = http_client.post(url=url, headers=headers, params=query_params)
|
||||
else:
|
||||
raise ValueError(f"Unsupported HTTP method: {method}")
|
||||
|
||||
|
|
@ -307,6 +340,7 @@ class GenericContainerHandler:
|
|||
# Make request
|
||||
method = endpoint_config["method"].upper()
|
||||
returns_binary = endpoint_config.get("returns_binary", False)
|
||||
is_multipart = endpoint_config.get("is_multipart", False)
|
||||
|
||||
try:
|
||||
if method == "GET":
|
||||
|
|
@ -314,7 +348,11 @@ class GenericContainerHandler:
|
|||
elif method == "DELETE":
|
||||
response = await http_client.delete(url=url, headers=headers, params=query_params)
|
||||
elif method == "POST":
|
||||
response = await http_client.post(url=url, headers=headers, params=query_params)
|
||||
if is_multipart and "file" in kwargs:
|
||||
files, headers = _prepare_multipart_file_upload(kwargs["file"], headers)
|
||||
response = await http_client.post(url=url, headers=headers, params=query_params, files=files)
|
||||
else:
|
||||
response = await http_client.post(url=url, headers=headers, params=query_params)
|
||||
else:
|
||||
raise ValueError(f"Unsupported HTTP method: {method}")
|
||||
|
||||
|
|
|
|||
|
|
@ -203,12 +203,8 @@ class GenAIHubOrchestrationConfig(OpenAIGPTConfig):
|
|||
litellm_params: dict,
|
||||
headers: dict,
|
||||
) -> dict:
|
||||
supported_params = self.get_supported_openai_params(model)
|
||||
# Include extra params that passed validation (e.g., thinking_config for Gemini models via allowed_openai_params)
|
||||
extra_params = [k for k in optional_params if k not in supported_params and k not in {"tools", "model_version"}]
|
||||
supported_params = supported_params + extra_params
|
||||
model_params = {
|
||||
k: v for k, v in optional_params.items() if k in supported_params
|
||||
k: v for k, v in optional_params.items() if k not in {"tools", "model_version", "deployment_url"}
|
||||
}
|
||||
|
||||
model_version = optional_params.pop("model_version", "latest")
|
||||
|
|
|
|||
|
|
@ -405,7 +405,23 @@
|
|||
"supports_video_input": true,
|
||||
"supports_vision": true
|
||||
},
|
||||
|
||||
"amazon.nova-2-multimodal-embeddings-v1:0": {
|
||||
"litellm_provider": "bedrock",
|
||||
"max_input_tokens": 8172,
|
||||
"max_tokens": 8172,
|
||||
"mode": "embedding",
|
||||
"input_cost_per_token": 1.35e-7,
|
||||
"input_cost_per_image": 6e-5,
|
||||
"input_cost_per_video_per_second": 0.0007,
|
||||
"input_cost_per_audio_per_second": 0.00014,
|
||||
"output_cost_per_token": 0.0,
|
||||
"output_vector_size": 3072,
|
||||
"source": "https://us-east-1.console.aws.amazon.com/bedrock/home?region=us-east-1#/model-catalog/serverless/amazon.nova-2-multimodal-embeddings-v1:0",
|
||||
"supports_embedding_image_input": true,
|
||||
"supports_image_input": true,
|
||||
"supports_video_input": true,
|
||||
"supports_audio_input": true
|
||||
},
|
||||
"amazon.nova-micro-v1:0": {
|
||||
"input_cost_per_token": 3.5e-08,
|
||||
"litellm_provider": "bedrock_converse",
|
||||
|
|
@ -4893,6 +4909,15 @@
|
|||
"/v1/images/generations"
|
||||
]
|
||||
},
|
||||
"azure_ai/flux.2-pro": {
|
||||
"litellm_provider": "azure_ai",
|
||||
"mode": "image_generation",
|
||||
"output_cost_per_image": 0.04,
|
||||
"source": "https://ai.azure.com/explore/models/flux.2-pro/version/1/registry/azureml-blackforestlabs",
|
||||
"supported_endpoints": [
|
||||
"/v1/images/generations"
|
||||
]
|
||||
},
|
||||
"azure_ai/Llama-3.2-11B-Vision-Instruct": {
|
||||
"input_cost_per_token": 3.7e-07,
|
||||
"litellm_provider": "azure_ai",
|
||||
|
|
@ -32152,6 +32177,181 @@
|
|||
"output_cost_per_token": 2e-07,
|
||||
"litellm_provider": "fireworks_ai",
|
||||
"mode": "chat"
|
||||
},
|
||||
"llamagate/llama-3.1-8b": {
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 131072,
|
||||
"max_output_tokens": 8192,
|
||||
"input_cost_per_token": 3e-08,
|
||||
"output_cost_per_token": 5e-08,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": true
|
||||
},
|
||||
"llamagate/llama-3.2-3b": {
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 131072,
|
||||
"max_output_tokens": 8192,
|
||||
"input_cost_per_token": 4e-08,
|
||||
"output_cost_per_token": 8e-08,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": true
|
||||
},
|
||||
"llamagate/mistral-7b-v0.3": {
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 32768,
|
||||
"max_output_tokens": 8192,
|
||||
"input_cost_per_token": 1e-07,
|
||||
"output_cost_per_token": 1.5e-07,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": true
|
||||
},
|
||||
"llamagate/qwen3-8b": {
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 32768,
|
||||
"max_output_tokens": 8192,
|
||||
"input_cost_per_token": 4e-08,
|
||||
"output_cost_per_token": 1.4e-07,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": true
|
||||
},
|
||||
"llamagate/dolphin3-8b": {
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 128000,
|
||||
"max_output_tokens": 8192,
|
||||
"input_cost_per_token": 8e-08,
|
||||
"output_cost_per_token": 1.5e-07,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": true
|
||||
},
|
||||
"llamagate/deepseek-r1-8b": {
|
||||
"max_tokens": 16384,
|
||||
"max_input_tokens": 65536,
|
||||
"max_output_tokens": 16384,
|
||||
"input_cost_per_token": 1e-07,
|
||||
"output_cost_per_token": 2e-07,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": true,
|
||||
"supports_reasoning": true
|
||||
},
|
||||
"llamagate/deepseek-r1-7b-qwen": {
|
||||
"max_tokens": 16384,
|
||||
"max_input_tokens": 131072,
|
||||
"max_output_tokens": 16384,
|
||||
"input_cost_per_token": 8e-08,
|
||||
"output_cost_per_token": 1.5e-07,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": true,
|
||||
"supports_reasoning": true
|
||||
},
|
||||
"llamagate/openthinker-7b": {
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 32768,
|
||||
"max_output_tokens": 8192,
|
||||
"input_cost_per_token": 8e-08,
|
||||
"output_cost_per_token": 1.5e-07,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": true,
|
||||
"supports_reasoning": true
|
||||
},
|
||||
"llamagate/qwen2.5-coder-7b": {
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 32768,
|
||||
"max_output_tokens": 8192,
|
||||
"input_cost_per_token": 6e-08,
|
||||
"output_cost_per_token": 1.2e-07,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": true
|
||||
},
|
||||
"llamagate/deepseek-coder-6.7b": {
|
||||
"max_tokens": 4096,
|
||||
"max_input_tokens": 16384,
|
||||
"max_output_tokens": 4096,
|
||||
"input_cost_per_token": 6e-08,
|
||||
"output_cost_per_token": 1.2e-07,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": true
|
||||
},
|
||||
"llamagate/codellama-7b": {
|
||||
"max_tokens": 4096,
|
||||
"max_input_tokens": 16384,
|
||||
"max_output_tokens": 4096,
|
||||
"input_cost_per_token": 6e-08,
|
||||
"output_cost_per_token": 1.2e-07,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": true
|
||||
},
|
||||
"llamagate/qwen3-vl-8b": {
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 32768,
|
||||
"max_output_tokens": 8192,
|
||||
"input_cost_per_token": 1.5e-07,
|
||||
"output_cost_per_token": 5.5e-07,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": true,
|
||||
"supports_vision": true
|
||||
},
|
||||
"llamagate/llava-7b": {
|
||||
"max_tokens": 2048,
|
||||
"max_input_tokens": 4096,
|
||||
"max_output_tokens": 2048,
|
||||
"input_cost_per_token": 1e-07,
|
||||
"output_cost_per_token": 2e-07,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "chat",
|
||||
"supports_response_schema": true,
|
||||
"supports_vision": true
|
||||
},
|
||||
"llamagate/gemma3-4b": {
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 128000,
|
||||
"max_output_tokens": 8192,
|
||||
"input_cost_per_token": 3e-08,
|
||||
"output_cost_per_token": 8e-08,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_response_schema": true,
|
||||
"supports_vision": true
|
||||
},
|
||||
"llamagate/nomic-embed-text": {
|
||||
"max_tokens": 8192,
|
||||
"max_input_tokens": 8192,
|
||||
"input_cost_per_token": 2e-08,
|
||||
"output_cost_per_token": 0,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "embedding"
|
||||
},
|
||||
"llamagate/qwen3-embedding-8b": {
|
||||
"max_tokens": 40960,
|
||||
"max_input_tokens": 40960,
|
||||
"input_cost_per_token": 2e-08,
|
||||
"output_cost_per_token": 0,
|
||||
"litellm_provider": "llamagate",
|
||||
"mode": "embedding"
|
||||
}
|
||||
}
|
||||
|
||||
|
|
|
|||
|
|
@ -1532,6 +1532,7 @@ class UpdateTeamRequest(LiteLLMPydanticObjectBase):
|
|||
guardrails: Optional[List[str]] = None
|
||||
object_permission: Optional[LiteLLM_ObjectPermissionBase] = None
|
||||
team_member_budget: Optional[float] = None
|
||||
team_member_budget_duration: Optional[str] = None
|
||||
team_member_rpm_limit: Optional[int] = None
|
||||
team_member_tpm_limit: Optional[int] = None
|
||||
team_member_key_duration: Optional[str] = None
|
||||
|
|
|
|||
|
|
@ -43,7 +43,7 @@ def _get_container_provider_config(custom_llm_provider: str):
|
|||
raise ValueError(f"Container API not supported for provider: {custom_llm_provider}")
|
||||
|
||||
|
||||
def _create_handler_for_path_params(path_params: List[str], route_type: str, returns_binary: bool = False):
|
||||
def _create_handler_for_path_params(path_params: List[str], route_type: str, returns_binary: bool = False, is_multipart: bool = False):
|
||||
"""
|
||||
Dynamically create a handler with the correct path parameter signature.
|
||||
"""
|
||||
|
|
@ -63,6 +63,23 @@ def _create_handler_for_path_params(path_params: List[str], route_type: str, ret
|
|||
)
|
||||
return handler_binary_content
|
||||
|
||||
# For multipart file upload endpoints
|
||||
if is_multipart:
|
||||
async def handler_multipart_upload(
|
||||
request: Request,
|
||||
container_id: str,
|
||||
fastapi_response: Response,
|
||||
user_api_key_dict: UserAPIKeyAuth = Depends(user_api_key_auth),
|
||||
):
|
||||
return await _process_multipart_upload_request(
|
||||
request=request,
|
||||
fastapi_response=fastapi_response,
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
route_type=route_type,
|
||||
container_id=container_id,
|
||||
)
|
||||
return handler_multipart_upload
|
||||
|
||||
# Create handlers for different path parameter combinations
|
||||
if path_params == ["container_id"]:
|
||||
async def handler_container_id(
|
||||
|
|
@ -193,6 +210,83 @@ async def _process_binary_request(
|
|||
raise e
|
||||
|
||||
|
||||
async def _process_multipart_upload_request(
|
||||
request: Request,
|
||||
fastapi_response: Response,
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
route_type: str,
|
||||
container_id: str,
|
||||
):
|
||||
"""Process multipart file upload requests."""
|
||||
from litellm.proxy.common_utils.http_parsing_utils import (
|
||||
convert_upload_files_to_file_data,
|
||||
get_form_data,
|
||||
)
|
||||
from litellm.proxy.proxy_server import (
|
||||
general_settings,
|
||||
llm_router,
|
||||
proxy_config,
|
||||
proxy_logging_obj,
|
||||
select_data_generator,
|
||||
user_api_base,
|
||||
user_max_tokens,
|
||||
user_model,
|
||||
user_request_timeout,
|
||||
user_temperature,
|
||||
version,
|
||||
)
|
||||
|
||||
# Parse multipart form data and convert files
|
||||
form_data = await get_form_data(request)
|
||||
data = await convert_upload_files_to_file_data(form_data)
|
||||
|
||||
if "file" not in data:
|
||||
from fastapi import HTTPException
|
||||
raise HTTPException(status_code=400, detail="Missing required 'file' field")
|
||||
|
||||
# convert_upload_files_to_file_data returns list of tuples, extract single file
|
||||
file_list = data["file"]
|
||||
if isinstance(file_list, list) and len(file_list) > 0:
|
||||
data["file"] = file_list[0]
|
||||
|
||||
data["container_id"] = container_id
|
||||
|
||||
custom_llm_provider = (
|
||||
get_custom_llm_provider_from_request_headers(request=request)
|
||||
or get_custom_llm_provider_from_request_query(request=request)
|
||||
or "openai"
|
||||
)
|
||||
data["custom_llm_provider"] = custom_llm_provider
|
||||
|
||||
processor = ProxyBaseLLMRequestProcessing(data=data)
|
||||
try:
|
||||
return await processor.base_process_llm_request(
|
||||
request=request,
|
||||
fastapi_response=fastapi_response,
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
route_type=route_type, # type: ignore[arg-type]
|
||||
proxy_logging_obj=proxy_logging_obj,
|
||||
llm_router=llm_router,
|
||||
general_settings=general_settings,
|
||||
proxy_config=proxy_config,
|
||||
select_data_generator=select_data_generator,
|
||||
model=None,
|
||||
user_model=user_model,
|
||||
user_temperature=user_temperature,
|
||||
user_request_timeout=user_request_timeout,
|
||||
user_max_tokens=user_max_tokens,
|
||||
user_api_base=user_api_base,
|
||||
version=version,
|
||||
)
|
||||
except Exception as e:
|
||||
raise await processor._handle_llm_api_exception(
|
||||
e=e,
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
proxy_logging_obj=proxy_logging_obj,
|
||||
version=version,
|
||||
)
|
||||
|
||||
|
||||
async def _process_request(
|
||||
request: Request,
|
||||
fastapi_response: Response,
|
||||
|
|
@ -272,9 +366,10 @@ def register_container_file_endpoints(router: APIRouter) -> None:
|
|||
path_params = endpoint_config.get("path_params", [])
|
||||
route_type = endpoint_config["async_name"]
|
||||
returns_binary = endpoint_config.get("returns_binary", False)
|
||||
is_multipart = endpoint_config.get("is_multipart", False)
|
||||
|
||||
# Create handler with correct signature for path params
|
||||
handler = _create_handler_for_path_params(path_params, route_type, returns_binary)
|
||||
handler = _create_handler_for_path_params(path_params, route_type, returns_binary, is_multipart)
|
||||
|
||||
# Register routes
|
||||
route_method = getattr(router, method)
|
||||
|
|
|
|||
|
|
@ -112,6 +112,7 @@ class TeamMemberBudgetHandler:
|
|||
team_member_budget: Optional[float] = None,
|
||||
team_member_rpm_limit: Optional[int] = None,
|
||||
team_member_tpm_limit: Optional[int] = None,
|
||||
team_member_budget_duration: Optional[str] = None,
|
||||
) -> bool:
|
||||
"""Check if any team member limits are provided"""
|
||||
return any(
|
||||
|
|
@ -119,6 +120,7 @@ class TeamMemberBudgetHandler:
|
|||
team_member_budget is not None,
|
||||
team_member_rpm_limit is not None,
|
||||
team_member_tpm_limit is not None,
|
||||
team_member_budget_duration is not None,
|
||||
]
|
||||
)
|
||||
|
||||
|
|
@ -130,6 +132,7 @@ class TeamMemberBudgetHandler:
|
|||
team_member_budget: Optional[float] = None,
|
||||
team_member_rpm_limit: Optional[int] = None,
|
||||
team_member_tpm_limit: Optional[int] = None,
|
||||
team_member_budget_duration: Optional[str] = None,
|
||||
) -> dict:
|
||||
"""Create team member budget table with provided limits"""
|
||||
from litellm.proxy._types import BudgetNewRequest
|
||||
|
|
@ -147,7 +150,7 @@ class TeamMemberBudgetHandler:
|
|||
# Create budget request with all provided limits
|
||||
budget_request = BudgetNewRequest(
|
||||
budget_id=budget_id,
|
||||
budget_duration=data.budget_duration,
|
||||
budget_duration=data.budget_duration or team_member_budget_duration,
|
||||
)
|
||||
|
||||
if team_member_budget is not None:
|
||||
|
|
@ -156,6 +159,8 @@ class TeamMemberBudgetHandler:
|
|||
budget_request.rpm_limit = team_member_rpm_limit
|
||||
if team_member_tpm_limit is not None:
|
||||
budget_request.tpm_limit = team_member_tpm_limit
|
||||
if team_member_budget_duration is not None:
|
||||
budget_request.budget_duration = team_member_budget_duration
|
||||
|
||||
team_member_budget_table = await new_budget(
|
||||
budget_obj=budget_request,
|
||||
|
|
@ -182,6 +187,7 @@ class TeamMemberBudgetHandler:
|
|||
team_member_budget: Optional[float] = None,
|
||||
team_member_rpm_limit: Optional[int] = None,
|
||||
team_member_tpm_limit: Optional[int] = None,
|
||||
team_member_budget_duration: Optional[str] = None,
|
||||
) -> dict:
|
||||
"""Upsert team member budget table with provided limits"""
|
||||
from litellm.proxy._types import BudgetNewRequest
|
||||
|
|
@ -203,6 +209,8 @@ class TeamMemberBudgetHandler:
|
|||
budget_request.rpm_limit = team_member_rpm_limit
|
||||
if team_member_tpm_limit is not None:
|
||||
budget_request.tpm_limit = team_member_tpm_limit
|
||||
if team_member_budget_duration is not None:
|
||||
budget_request.budget_duration = team_member_budget_duration
|
||||
|
||||
budget_row = await update_budget(
|
||||
budget_obj=budget_request,
|
||||
|
|
@ -223,6 +231,7 @@ class TeamMemberBudgetHandler:
|
|||
team_member_budget=team_member_budget,
|
||||
team_member_rpm_limit=team_member_rpm_limit,
|
||||
team_member_tpm_limit=team_member_tpm_limit,
|
||||
team_member_budget_duration=team_member_budget_duration,
|
||||
)
|
||||
|
||||
# Remove team member fields from updated_kv
|
||||
|
|
@ -233,6 +242,7 @@ class TeamMemberBudgetHandler:
|
|||
def _clean_team_member_fields(data_dict: dict) -> None:
|
||||
"""Remove team member fields from data dictionary"""
|
||||
data_dict.pop("team_member_budget", None)
|
||||
data_dict.pop("team_member_budget_duration", None)
|
||||
data_dict.pop("team_member_rpm_limit", None)
|
||||
data_dict.pop("team_member_tpm_limit", None)
|
||||
|
||||
|
|
@ -1214,6 +1224,7 @@ async def update_team( # noqa: PLR0915
|
|||
- disable_global_guardrails: Optional[bool] - Whether to disable global guardrails for the key.
|
||||
- object_permission: Optional[LiteLLM_ObjectPermissionBase] - team-specific object permission. Example - {"vector_stores": ["vector_store_1", "vector_store_2"], "agents": ["agent_1", "agent_2"], "agent_access_groups": ["dev_group"]}. IF null or {} then no object permission.
|
||||
- team_member_budget: Optional[float] - The maximum budget allocated to an individual team member.
|
||||
- team_member_budget_duration: Optional[str] - The duration of the budget for the team member. Doc [here](https://docs.litellm.ai/docs/proxy/team_budgets)
|
||||
- team_member_rpm_limit: Optional[int] - The RPM (Requests Per Minute) limit for individual team members.
|
||||
- team_member_tpm_limit: Optional[int] - The TPM (Tokens Per Minute) limit for individual team members.
|
||||
- team_member_key_duration: Optional[str] - The duration for a team member's key. e.g. "1d", "1w", "1mo"
|
||||
|
|
@ -1349,6 +1360,7 @@ async def update_team( # noqa: PLR0915
|
|||
team_member_budget=data.team_member_budget,
|
||||
team_member_rpm_limit=data.team_member_rpm_limit,
|
||||
team_member_tpm_limit=data.team_member_tpm_limit,
|
||||
team_member_budget_duration=data.team_member_budget_duration,
|
||||
):
|
||||
updated_kv = await TeamMemberBudgetHandler.upsert_team_member_budget_table(
|
||||
team_table=existing_team_row,
|
||||
|
|
@ -1357,6 +1369,7 @@ async def update_team( # noqa: PLR0915
|
|||
team_member_budget=data.team_member_budget,
|
||||
team_member_rpm_limit=data.team_member_rpm_limit,
|
||||
team_member_tpm_limit=data.team_member_tpm_limit,
|
||||
team_member_budget_duration=data.team_member_budget_duration,
|
||||
)
|
||||
else:
|
||||
TeamMemberBudgetHandler._clean_team_member_fields(updated_kv)
|
||||
|
|
|
|||
|
|
@ -2,4 +2,7 @@ model_list:
|
|||
- model_name: anthropic/*
|
||||
litellm_params:
|
||||
model: anthropic/*
|
||||
- model_name: openai/*
|
||||
litellm_params:
|
||||
model: openai/*
|
||||
|
||||
|
|
|
|||
|
|
@ -38,6 +38,7 @@ ROUTE_ENDPOINT_MAPPING = {
|
|||
"aretrieve_container": "/containers/{container_id}",
|
||||
"adelete_container": "/containers/{container_id}",
|
||||
# Auto-generated container file routes
|
||||
"aupload_container_file": "/containers/{container_id}/files",
|
||||
"alist_container_files": "/containers/{container_id}/files",
|
||||
"aretrieve_container_file": "/containers/{container_id}/files/{file_id}",
|
||||
"adelete_container_file": "/containers/{container_id}/files/{file_id}",
|
||||
|
|
@ -144,6 +145,7 @@ async def route_request(
|
|||
"alist_containers",
|
||||
"aretrieve_container",
|
||||
"adelete_container",
|
||||
"aupload_container_file",
|
||||
"alist_container_files",
|
||||
"aretrieve_container_file",
|
||||
"adelete_container_file",
|
||||
|
|
@ -204,6 +206,7 @@ async def route_request(
|
|||
"alist_containers",
|
||||
"aretrieve_container",
|
||||
"adelete_container",
|
||||
"aupload_container_file",
|
||||
"alist_container_files",
|
||||
"aretrieve_container_file",
|
||||
"adelete_container_file",
|
||||
|
|
@ -287,6 +290,7 @@ async def route_request(
|
|||
"alist_containers",
|
||||
"aretrieve_container",
|
||||
"adelete_container",
|
||||
"aupload_container_file",
|
||||
"alist_container_files",
|
||||
"aretrieve_container_file",
|
||||
"adelete_container_file",
|
||||
|
|
|
|||
|
|
@ -4003,6 +4003,8 @@ class Router:
|
|||
"retrieve_container",
|
||||
"adelete_container",
|
||||
"delete_container",
|
||||
"aupload_container_file",
|
||||
"upload_container_file",
|
||||
"alist_container_files",
|
||||
"list_container_files",
|
||||
"aretrieve_container_file",
|
||||
|
|
@ -4154,6 +4156,7 @@ class Router:
|
|||
"alist_containers",
|
||||
"aretrieve_container",
|
||||
"adelete_container",
|
||||
"aupload_container_file",
|
||||
"alist_container_files",
|
||||
"aretrieve_container_file",
|
||||
"adelete_container_file",
|
||||
|
|
|
|||
|
|
@ -14,3 +14,4 @@ class ArizeConfig(BaseModel):
|
|||
api_key: Optional[str] = None
|
||||
protocol: Protocol
|
||||
endpoint: str
|
||||
project_name: Optional[str] = None
|
||||
|
|
|
|||
|
|
@ -324,6 +324,8 @@ class CallTypes(str, Enum):
|
|||
adelete_container = "adelete_container"
|
||||
list_container_files = "list_container_files"
|
||||
alist_container_files = "alist_container_files"
|
||||
upload_container_file = "upload_container_file"
|
||||
aupload_container_file = "aupload_container_file"
|
||||
|
||||
acancel_fine_tuning_job = "acancel_fine_tuning_job"
|
||||
cancel_fine_tuning_job = "cancel_fine_tuning_job"
|
||||
|
|
|
|||
|
|
@ -4909,6 +4909,15 @@
|
|||
"/v1/images/generations"
|
||||
]
|
||||
},
|
||||
"azure_ai/flux.2-pro": {
|
||||
"litellm_provider": "azure_ai",
|
||||
"mode": "image_generation",
|
||||
"output_cost_per_image": 0.04,
|
||||
"source": "https://ai.azure.com/explore/models/flux.2-pro/version/1/registry/azureml-blackforestlabs",
|
||||
"supported_endpoints": [
|
||||
"/v1/images/generations"
|
||||
]
|
||||
},
|
||||
"azure_ai/Llama-3.2-11B-Vision-Instruct": {
|
||||
"input_cost_per_token": 3.7e-07,
|
||||
"litellm_provider": "azure_ai",
|
||||
|
|
|
|||
10
poetry.lock
generated
10
poetry.lock
generated
|
|
@ -1,4 +1,4 @@
|
|||
# This file is automatically @generated by Poetry 2.2.1 and should not be changed by hand.
|
||||
# This file is automatically @generated by Poetry 2.2.0 and should not be changed by hand.
|
||||
|
||||
[[package]]
|
||||
name = "aiofiles"
|
||||
|
|
@ -3081,15 +3081,15 @@ files = [
|
|||
|
||||
[[package]]
|
||||
name = "litellm-proxy-extras"
|
||||
version = "0.4.16"
|
||||
version = "0.4.18"
|
||||
description = "Additional files for the LiteLLM Proxy. Reduces the size of the main litellm package."
|
||||
optional = true
|
||||
python-versions = "!=2.7.*,!=3.0.*,!=3.1.*,!=3.2.*,!=3.3.*,!=3.4.*,!=3.5.*,!=3.6.*,!=3.7.*,>=3.8"
|
||||
groups = ["main"]
|
||||
markers = "extra == \"proxy\""
|
||||
files = [
|
||||
{file = "litellm_proxy_extras-0.4.16-py3-none-any.whl", hash = "sha256:5651e777c7f4c0e87c6722971bca19b8f40f417b08f74001cab2d0a5b1c63a91"},
|
||||
{file = "litellm_proxy_extras-0.4.16.tar.gz", hash = "sha256:ff1ee4ea119318b471bb71a99d8bc941159d4d2c09bee797dd29768e9504befb"},
|
||||
{file = "litellm_proxy_extras-0.4.18-py3-none-any.whl", hash = "sha256:c3edee68bf8eb073c6158dcf7df05727dfc829e63c03a617fcb48853d11490df"},
|
||||
{file = "litellm_proxy_extras-0.4.18.tar.gz", hash = "sha256:898b28e3e74acdc29142906b84787ab05a90e30aa3c0c8aee849915e3a16adb3"},
|
||||
]
|
||||
|
||||
[[package]]
|
||||
|
|
@ -7981,4 +7981,4 @@ utils = ["numpydoc"]
|
|||
[metadata]
|
||||
lock-version = "2.1"
|
||||
python-versions = ">=3.9,<4.0"
|
||||
content-hash = "7eed2b2c25173a275ac83c55fd901b9b84663b1d7daa54f0e78b30bf1c8f0e3e"
|
||||
content-hash = "e9fd12b5ccc703ec156d98877452417083e3ac18b5970cb3a58c3bde09d267bb"
|
||||
|
|
|
|||
|
|
@ -20,16 +20,14 @@
|
|||
"skills": "Supports /skills endpoint",
|
||||
"interactions": "Supports /interactions endpoint (Google AI Interactions API)",
|
||||
"a2a_(Agent Gateway)": "Supports /a2a/{agent}/message/send endpoint (A2A Protocol)",
|
||||
"create_container": "Supports POST /containers endpoint",
|
||||
"list_containers": "Supports GET /containers endpoint",
|
||||
"retrieve_container": "Supports GET /containers/{id} endpoint",
|
||||
"delete_container": "Supports DELETE /containers/{id} endpoint",
|
||||
"create_container_file": "Supports POST /containers/{id}/files endpoint",
|
||||
"list_container_files": "Supports GET /containers/{id}/files endpoint",
|
||||
"retrieve_container_file": "Supports GET /containers/{id}/files/{file_id} endpoint",
|
||||
"retrieve_container_file_content": "Supports GET /containers/{id}/files/{file_id}/content endpoint",
|
||||
"delete_container_file": "Supports DELETE /containers/{id}/files/{file_id} endpoint",
|
||||
"compact": "Supports /responses/compact endpoint"
|
||||
"container": "Supports OpenAI's /containers endpoint",
|
||||
"container_file": "Supports OpenAI's /containers/{id}/files endpoint",
|
||||
"compact": "Supports /responses/compact endpoint",
|
||||
"files": "Supports /files endpoint for file operations",
|
||||
"image_edits": "Supports /images/edits endpoint for image editing",
|
||||
"vector_stores_create": "Supports creating a new vector store via /vector_stores endpoint",
|
||||
"vector_stores_search": "Supports searching a vector store via /vector_stores/{id}/search endpoint",
|
||||
"video_generations": "Supports /videos/generations endpoint for video generation"
|
||||
}
|
||||
}
|
||||
},
|
||||
|
|
@ -122,7 +120,8 @@
|
|||
"rerank": false,
|
||||
"skills": true,
|
||||
"a2a": true,
|
||||
"interactions": true
|
||||
"interactions": true,
|
||||
"count_tokens": true
|
||||
}
|
||||
},
|
||||
"anthropic_text": {
|
||||
|
|
@ -211,7 +210,13 @@
|
|||
"batches": false,
|
||||
"rerank": true,
|
||||
"a2a": true,
|
||||
"interactions": true
|
||||
"interactions": true,
|
||||
"bedrock_invoke": true,
|
||||
"bedrock_converse": true,
|
||||
"vector_stores_search": true,
|
||||
"count_tokens": true,
|
||||
"rag_ingest": true,
|
||||
"rag_query": true
|
||||
}
|
||||
},
|
||||
"sagemaker": {
|
||||
|
|
@ -263,7 +268,11 @@
|
|||
"batches": true,
|
||||
"rerank": false,
|
||||
"a2a": true,
|
||||
"interactions": true
|
||||
"interactions": true,
|
||||
"vector_stores_search": true,
|
||||
"assistants": true,
|
||||
"fine_tuning": true,
|
||||
"text_completion": true
|
||||
}
|
||||
},
|
||||
"azure_ai": {
|
||||
|
|
@ -275,6 +284,7 @@
|
|||
"responses": true,
|
||||
"embeddings": true,
|
||||
"image_generations": true,
|
||||
"image_edits": true,
|
||||
"audio_transcriptions": true,
|
||||
"audio_speech": true,
|
||||
"moderations": true,
|
||||
|
|
@ -282,7 +292,9 @@
|
|||
"rerank": false,
|
||||
"ocr": true,
|
||||
"a2a": true,
|
||||
"interactions": true
|
||||
"interactions": true,
|
||||
"vector_stores_create": true,
|
||||
"vector_stores_search": true
|
||||
}
|
||||
},
|
||||
"azure_ai/doc-intelligence": {
|
||||
|
|
@ -918,29 +930,19 @@
|
|||
"embeddings": true,
|
||||
"image_generations": true,
|
||||
"audio_transcriptions": false,
|
||||
"audio_speech": false,
|
||||
"audio_speech": true,
|
||||
"moderations": false,
|
||||
"batches": false,
|
||||
"rerank": false,
|
||||
"ocr": true,
|
||||
"a2a": true,
|
||||
"interactions": true
|
||||
}
|
||||
},
|
||||
"vertex_ai/chirp": {
|
||||
"display_name": "Google - Vertex AI Chirp3 HD (`vertex_ai/chirp`)",
|
||||
"url": "https://docs.litellm.ai/docs/providers/vertex_speech",
|
||||
"endpoints": {
|
||||
"chat_completions": false,
|
||||
"messages": false,
|
||||
"responses": false,
|
||||
"embeddings": false,
|
||||
"image_generations": false,
|
||||
"audio_transcriptions": false,
|
||||
"audio_speech": true,
|
||||
"moderations": false,
|
||||
"batches": false,
|
||||
"rerank": false
|
||||
"interactions": true,
|
||||
"vector_stores_search": true,
|
||||
"count_tokens": true,
|
||||
"fine_tuning": true,
|
||||
"rag_ingest": true,
|
||||
"rag_query": true,
|
||||
"generateContent": true
|
||||
}
|
||||
},
|
||||
"gemini": {
|
||||
|
|
@ -958,7 +960,12 @@
|
|||
"batches": false,
|
||||
"rerank": false,
|
||||
"interactions": true,
|
||||
"a2a": true
|
||||
"a2a": true,
|
||||
"vector_stores_search": true,
|
||||
"count_tokens": true,
|
||||
"rag_ingest": true,
|
||||
"realtime": true,
|
||||
"generateContent": true
|
||||
}
|
||||
},
|
||||
"gradient_ai": {
|
||||
|
|
@ -1511,18 +1518,21 @@
|
|||
"moderations": true,
|
||||
"batches": true,
|
||||
"rerank": false,
|
||||
"create_container": true,
|
||||
"list_containers": true,
|
||||
"retrieve_container": true,
|
||||
"delete_container": true,
|
||||
"create_container_file": false,
|
||||
"list_container_files": true,
|
||||
"retrieve_container_file": true,
|
||||
"retrieve_container_file_content": true,
|
||||
"delete_container_file": true,
|
||||
"container": true,
|
||||
"compact": true,
|
||||
"a2a": true,
|
||||
"interactions": true
|
||||
"interactions": true,
|
||||
"vector_store_files": true,
|
||||
"vector_stores_create": true,
|
||||
"vector_stores_search": true,
|
||||
"assistants": true,
|
||||
"container_files": true,
|
||||
"fine_tuning": true,
|
||||
"image_variations": true,
|
||||
"rag_ingest": true,
|
||||
"rag_query": true,
|
||||
"realtime": true,
|
||||
"text_completion": true
|
||||
}
|
||||
},
|
||||
"openai_like": {
|
||||
|
|
@ -1538,7 +1548,8 @@
|
|||
"audio_speech": false,
|
||||
"moderations": false,
|
||||
"batches": false,
|
||||
"rerank": false
|
||||
"rerank": false,
|
||||
"assistants": true
|
||||
}
|
||||
},
|
||||
"openrouter": {
|
||||
|
|
@ -1897,34 +1908,13 @@
|
|||
"display_name": "Topaz (`topaz`)",
|
||||
"url": "https://docs.litellm.ai/docs/providers/topaz",
|
||||
"endpoints": {
|
||||
"chat_completions": true,
|
||||
"messages": true,
|
||||
"responses": true,
|
||||
"embeddings": false,
|
||||
"image_generations": false,
|
||||
"audio_transcriptions": false,
|
||||
"audio_speech": false,
|
||||
"moderations": false,
|
||||
"batches": false,
|
||||
"rerank": false,
|
||||
"a2a": true,
|
||||
"interactions": true
|
||||
"image_variations": true
|
||||
}
|
||||
},
|
||||
"tavily": {
|
||||
"display_name": "Tavily (`tavily`)",
|
||||
"url": "https://docs.litellm.ai/docs/search/tavily",
|
||||
"endpoints": {
|
||||
"chat_completions": false,
|
||||
"messages": false,
|
||||
"responses": false,
|
||||
"embeddings": false,
|
||||
"image_generations": false,
|
||||
"audio_transcriptions": false,
|
||||
"audio_speech": false,
|
||||
"moderations": false,
|
||||
"batches": false,
|
||||
"rerank": false,
|
||||
"search": true
|
||||
}
|
||||
},
|
||||
|
|
@ -2137,7 +2127,7 @@
|
|||
"moderations": false,
|
||||
"batches": false,
|
||||
"rerank": false,
|
||||
"vector_stores": true,
|
||||
"vector_stores_create": true,
|
||||
"a2a": true,
|
||||
"interactions": true
|
||||
}
|
||||
|
|
@ -2247,6 +2237,340 @@
|
|||
"a2a": true,
|
||||
"interactions": true
|
||||
}
|
||||
},
|
||||
"gigachat": {
|
||||
"display_name": "GigaChat (`gigachat`)",
|
||||
"url": "https://docs.litellm.ai/docs/providers/gigachat",
|
||||
"endpoints": {
|
||||
"chat_completions": true,
|
||||
"messages": true,
|
||||
"responses": true,
|
||||
"embeddings": true
|
||||
}
|
||||
},
|
||||
"google_pse": {
|
||||
"display_name": "Google PSE (`google_pse`)",
|
||||
"url": "https://docs.litellm.ai/docs/search/google_pse",
|
||||
"endpoints": {
|
||||
"search": true
|
||||
}
|
||||
},
|
||||
"milvus": {
|
||||
"display_name": "Milvus (`milvus`)",
|
||||
"url": "https://docs.litellm.ai/docs/providers/milvus_vector_stores",
|
||||
"endpoints": {
|
||||
"vector_stores_search": true
|
||||
}
|
||||
},
|
||||
"minimax": {
|
||||
"display_name": "Minimax (`minimax`)",
|
||||
"url": "https://docs.litellm.ai/docs/providers/minimax",
|
||||
"endpoints": {
|
||||
"chat_completions": true,
|
||||
"messages": true,
|
||||
"responses": true
|
||||
}
|
||||
},
|
||||
"pg_vector": {
|
||||
"display_name": "PG Vector (`pg_vector`)",
|
||||
"url": "https://docs.litellm.ai/docs/providers/pg_vector",
|
||||
"endpoints": {
|
||||
"vector_stores_search": true
|
||||
}
|
||||
},
|
||||
"helicone": {
|
||||
"display_name": "Helicone (`helicone`)",
|
||||
"url": "https://docs.litellm.ai/docs/providers/helicone",
|
||||
"endpoints": {
|
||||
"chat_completions": true,
|
||||
"messages": true,
|
||||
"responses": true
|
||||
}
|
||||
},
|
||||
"llamagate": {
|
||||
"display_name": "LlamaGate (`llamagate`)",
|
||||
"url": "https://docs.litellm.ai/docs/providers/llamagate",
|
||||
"endpoints": {
|
||||
"chat_completions": true,
|
||||
"messages": true,
|
||||
"responses": true
|
||||
}
|
||||
},
|
||||
"xiaomi_mimo": {
|
||||
"display_name": "Xiaomi Mimo (`xiaomi_mimo`)",
|
||||
"url": "https://docs.litellm.ai/docs/providers/xiaomi_mimo",
|
||||
"endpoints": {
|
||||
"chat_completions": true,
|
||||
"messages": true,
|
||||
"responses": true
|
||||
}
|
||||
}
|
||||
},
|
||||
"endpoints": {
|
||||
"a2a": {
|
||||
"docs_label": "a2a",
|
||||
"display_name": "A2A (Agent-to-Agent) protocol for agent communication",
|
||||
"leftnav_label": "/a2a",
|
||||
"provider_json_field": "a2a",
|
||||
"url": "https://docs.litellm.ai/docs/a2a",
|
||||
"bridges_to_chat_completion": true
|
||||
},
|
||||
"messages": {
|
||||
"docs_label": "anthropic_unified",
|
||||
"display_name": "Anthropic /v1/messages API",
|
||||
"leftnav_label": "/messages",
|
||||
"provider_json_field": "messages",
|
||||
"url": "https://docs.litellm.ai/docs/anthropic_unified",
|
||||
"bridges_to_chat_completion": true
|
||||
},
|
||||
"anthropic_count_tokens": {
|
||||
"docs_label": "anthropic_count_tokens",
|
||||
"display_name": "Anthropic /v1/messages/count_tokens API",
|
||||
"leftnav_label": "/count_tokens",
|
||||
"provider_json_field": "count_tokens",
|
||||
"url": "https://docs.litellm.ai/docs/anthropic_count_tokens"
|
||||
},
|
||||
"apply_guardrail": {
|
||||
"docs_label": "apply_guardrail",
|
||||
"display_name": "Unified Apply Guardrail API",
|
||||
"leftnav_label": "/guardrails/apply_guardrail",
|
||||
"provider_json_field": "apply_guardrail",
|
||||
"url": "https://docs.litellm.ai/docs/apply_guardrail"
|
||||
},
|
||||
"assistants": {
|
||||
"docs_label": "assistants",
|
||||
"display_name": "OpenAI Assistants API",
|
||||
"leftnav_label": "/assistants",
|
||||
"provider_json_field": "assistants",
|
||||
"url": "https://docs.litellm.ai/docs/assistants"
|
||||
},
|
||||
"audio_transcription": {
|
||||
"docs_label": "audio_transcription",
|
||||
"display_name": "Audio Transcription API",
|
||||
"leftnav_label": "/audio/transcriptions",
|
||||
"provider_json_field": "audio_transcriptions",
|
||||
"url": "https://docs.litellm.ai/docs/audio_transcription"
|
||||
},
|
||||
"batches": {
|
||||
"docs_label": "batches",
|
||||
"display_name": "Batches API",
|
||||
"leftnav_label": "/batches",
|
||||
"provider_json_field": "batches",
|
||||
"url": "https://docs.litellm.ai/docs/batches"
|
||||
},
|
||||
"bedrock_invoke": {
|
||||
"docs_label": "bedrock_invoke",
|
||||
"display_name": "Bedrock Invoke API",
|
||||
"leftnav_label": "/invoke",
|
||||
"provider_json_field": "bedrock_invoke",
|
||||
"url": "https://docs.litellm.ai/docs/bedrock_invoke"
|
||||
},
|
||||
"bedrock_converse": {
|
||||
"docs_label": "bedrock_converse",
|
||||
"display_name": "Bedrock Converse API",
|
||||
"leftnav_label": "/converse",
|
||||
"provider_json_field": "bedrock_converse",
|
||||
"url": "https://docs.litellm.ai/docs/bedrock_converse"
|
||||
},
|
||||
"chat_completions": {
|
||||
"docs_label": "chat_completions",
|
||||
"display_name": "Chat Completions API",
|
||||
"leftnav_label": "/chat/completions",
|
||||
"provider_json_field": "chat_completions",
|
||||
"url": "https://docs.litellm.ai/docs/chat_completions"
|
||||
},
|
||||
"container_files": {
|
||||
"docs_label": "container_files",
|
||||
"display_name": "OpenAI Container Files API",
|
||||
"leftnav_label": "/create/container/files",
|
||||
"provider_json_field": "container_files",
|
||||
"url": "https://docs.litellm.ai/docs/container_files"
|
||||
},
|
||||
"container": {
|
||||
"docs_label": "containers",
|
||||
"display_name": "OpenAI Containers API",
|
||||
"leftnav_label": "/container",
|
||||
"provider_json_field": "container",
|
||||
"url": "https://docs.litellm.ai/docs/containers"
|
||||
},
|
||||
"embeddings": {
|
||||
"docs_label": "embedding/supported_embedding",
|
||||
"display_name": "Embedding API (OpenAI Format)",
|
||||
"leftnav_label": "/embeddings",
|
||||
"provider_json_field": "embeddings",
|
||||
"url": "https://docs.litellm.ai/docs/embedding/supported_embedding"
|
||||
},
|
||||
"files": {
|
||||
"docs_label": "files",
|
||||
"display_name": "OpenAI Files API",
|
||||
"leftnav_label": "/files",
|
||||
"provider_json_field": "files",
|
||||
"url": "https://docs.litellm.ai/docs/proxy/litellm_managed_files"
|
||||
},
|
||||
"fine_tuning": {
|
||||
"docs_label": "fine_tuning",
|
||||
"display_name": "OpenAI Fine-Tuning API",
|
||||
"leftnav_label": "/fine_tuning",
|
||||
"provider_json_field": "fine_tuning",
|
||||
"url": "https://docs.litellm.ai/docs/proxy/managed_finetuning"
|
||||
},
|
||||
"generateContent": {
|
||||
"docs_label": "generateContent",
|
||||
"display_name": "Google's GenerateContent API",
|
||||
"leftnav_label": "/generateContent",
|
||||
"provider_json_field": "generateContent",
|
||||
"url": "https://docs.litellm.ai/docs/generateContent",
|
||||
"bridges_to_chat_completion": true
|
||||
},
|
||||
"image_edits": {
|
||||
"docs_label": "image_edits",
|
||||
"display_name": "OpenAI Images Edits API",
|
||||
"leftnav_label": "/images/edits",
|
||||
"provider_json_field": "image_edits",
|
||||
"url": "https://docs.litellm.ai/docs/image_edits"
|
||||
},
|
||||
"image_generations": {
|
||||
"docs_label": "image_generation",
|
||||
"display_name": "OpenAI Images Generations API",
|
||||
"leftnav_label": "/images/generations",
|
||||
"provider_json_field": "image_generations",
|
||||
"url": "https://docs.litellm.ai/docs/image_generation"
|
||||
},
|
||||
"image_variations": {
|
||||
"docs_label": "image_variations",
|
||||
"display_name": "OpenAI Images Variations API",
|
||||
"leftnav_label": "/images/variations",
|
||||
"provider_json_field": "image_variations",
|
||||
"url": "https://docs.litellm.ai/docs/image_variations"
|
||||
},
|
||||
"interactions": {
|
||||
"docs_label": "interactions",
|
||||
"display_name": "Google Interactions API",
|
||||
"leftnav_label": "/interactions",
|
||||
"provider_json_field": "interactions",
|
||||
"url": "https://docs.litellm.ai/docs/interactions",
|
||||
"bridges_to_chat_completion": true
|
||||
},
|
||||
"mcp": {
|
||||
"docs_label": "mcp",
|
||||
"display_name": "Model Context Protocol (MCP)",
|
||||
"leftnav_label": "/mcp",
|
||||
"provider_json_field": "mcp",
|
||||
"url": "https://docs.litellm.ai/docs/mcp"
|
||||
},
|
||||
"moderation": {
|
||||
"docs_label": "moderation",
|
||||
"display_name": "OpenAI Moderation API",
|
||||
"leftnav_label": "/moderations",
|
||||
"provider_json_field": "moderations",
|
||||
"url": "https://docs.litellm.ai/docs/moderation"
|
||||
},
|
||||
"ocr": {
|
||||
"docs_label": "ocr",
|
||||
"display_name": "OCR API (Mistral Format)",
|
||||
"leftnav_label": "/ocr",
|
||||
"provider_json_field": "ocr",
|
||||
"url": "https://docs.litellm.ai/docs/ocr"
|
||||
},
|
||||
"rag_ingest": {
|
||||
"docs_label": "rag_ingest",
|
||||
"display_name": "RAG Ingest API",
|
||||
"leftnav_label": "/rag/ingest",
|
||||
"provider_json_field": "rag_ingest",
|
||||
"url": "https://docs.litellm.ai/docs/rag_ingest"
|
||||
},
|
||||
"rag_query": {
|
||||
"docs_label": "rag_query",
|
||||
"display_name": "RAG Query API",
|
||||
"leftnav_label": "/rag/query",
|
||||
"provider_json_field": "rag_query",
|
||||
"url": "https://docs.litellm.ai/docs/rag_query"
|
||||
},
|
||||
"realtime": {
|
||||
"docs_label": "realtime",
|
||||
"display_name": "OpenAI Realtime API",
|
||||
"leftnav_label": "/realtime",
|
||||
"provider_json_field": "realtime",
|
||||
"url": "https://docs.litellm.ai/docs/realtime"
|
||||
},
|
||||
"rerank": {
|
||||
"docs_label": "rerank",
|
||||
"display_name": "Rerank API (Cohere Format)",
|
||||
"leftnav_label": "/rerank",
|
||||
"provider_json_field": "rerank",
|
||||
"url": "https://docs.litellm.ai/docs/rerank"
|
||||
},
|
||||
"responses": {
|
||||
"docs_label": "response_api",
|
||||
"display_name": "Responses API (OpenAI Format)",
|
||||
"leftnav_label": "/responses",
|
||||
"provider_json_field": "responses",
|
||||
"url": "https://docs.litellm.ai/docs/response_api",
|
||||
"bridges_to_chat_completion": true
|
||||
},
|
||||
"response_api_compact": {
|
||||
"docs_label": "response_api_compact",
|
||||
"display_name": "Responses API (OpenAI Format)",
|
||||
"leftnav_label": "/responses",
|
||||
"provider_json_field": "compact",
|
||||
"url": "https://docs.litellm.ai/docs/response_api"
|
||||
},
|
||||
"search": {
|
||||
"docs_label": "search",
|
||||
"display_name": "Search API",
|
||||
"leftnav_label": "/search",
|
||||
"provider_json_field": "search",
|
||||
"url": "https://docs.litellm.ai/docs/search"
|
||||
},
|
||||
"skills": {
|
||||
"docs_label": "skills",
|
||||
"display_name": "Anthropic Skills API",
|
||||
"leftnav_label": "/skills",
|
||||
"provider_json_field": "skills",
|
||||
"url": "https://docs.litellm.ai/docs/skills"
|
||||
},
|
||||
"text_completion": {
|
||||
"docs_label": "text_completion",
|
||||
"display_name": "Completions API (OpenAI Format)",
|
||||
"leftnav_label": "/completions",
|
||||
"provider_json_field": "text_completion",
|
||||
"url": "https://docs.litellm.ai/docs/text_completion",
|
||||
"bridges_to_chat_completion": true
|
||||
},
|
||||
"text_to_speech": {
|
||||
"docs_label": "text_to_speech",
|
||||
"display_name": "Text-to-Speech API (OpenAI Format)",
|
||||
"leftnav_label": "/audio/speech",
|
||||
"provider_json_field": "audio_speech",
|
||||
"url": "https://docs.litellm.ai/docs/text_to_speech"
|
||||
},
|
||||
"vector_store_files": {
|
||||
"docs_label": "vector_store_files",
|
||||
"display_name": "OpenAI Vector Store Files API",
|
||||
"leftnav_label": "/vector_stores/files",
|
||||
"provider_json_field": "vector_store_files",
|
||||
"url": "https://docs.litellm.ai/docs/vector_store_files"
|
||||
},
|
||||
"vector_stores_create": {
|
||||
"docs_label": "vector_stores_create",
|
||||
"display_name": "OpenAI Vector Stores Create API",
|
||||
"leftnav_label": "/vector_stores/create",
|
||||
"provider_json_field": "vector_stores_create",
|
||||
"url": "https://docs.litellm.ai/docs/vector_stores/create"
|
||||
},
|
||||
"vector_stores_search": {
|
||||
"docs_label": "vector_stores_search",
|
||||
"display_name": "OpenAI Vector Stores Search API",
|
||||
"leftnav_label": "/vector_stores/search",
|
||||
"provider_json_field": "vector_stores_search",
|
||||
"url": "https://docs.litellm.ai/docs/vector_stores/search"
|
||||
},
|
||||
"videos": {
|
||||
"docs_label": "videos",
|
||||
"display_name": "OpenAI Video Generation API",
|
||||
"leftnav_label": "/videos",
|
||||
"provider_json_field": "video_generations",
|
||||
"url": "https://docs.litellm.ai/docs/videos"
|
||||
}
|
||||
}
|
||||
}
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "litellm"
|
||||
version = "1.80.11"
|
||||
version = "1.80.12"
|
||||
description = "Library to easily interface with LLM API providers"
|
||||
authors = ["BerriAI"]
|
||||
license = "MIT"
|
||||
|
|
@ -59,7 +59,7 @@ websockets = {version = "^15.0.1", optional = true}
|
|||
boto3 = {version = "1.36.0", optional = true}
|
||||
redisvl = {version = "^0.4.1", optional = true, markers = "python_version >= '3.9' and python_version < '3.14'"}
|
||||
mcp = {version = "^1.21.2", optional = true, python = ">=3.10"}
|
||||
litellm-proxy-extras = {version = "0.4.17", optional = true}
|
||||
litellm-proxy-extras = {version = "0.4.18", optional = true}
|
||||
rich = {version = "13.7.1", optional = true}
|
||||
litellm-enterprise = {version = "0.1.27", optional = true}
|
||||
diskcache = {version = "^5.6.1", optional = true}
|
||||
|
|
@ -167,7 +167,7 @@ requires = ["poetry-core", "wheel"]
|
|||
build-backend = "poetry.core.masonry.api"
|
||||
|
||||
[tool.commitizen]
|
||||
version = "1.80.11"
|
||||
version = "1.80.12"
|
||||
version_files = [
|
||||
"pyproject.toml:^version"
|
||||
]
|
||||
|
|
|
|||
|
|
@ -15,7 +15,7 @@ redis==5.2.1 # redis caching
|
|||
prisma==0.11.0 # for db
|
||||
nodejs-wheel-binaries==24.12.0 ## required by prisma for migrations, prevents runtime download (updated from nodejs-bin for security fixes)
|
||||
mangum==0.17.0 # for aws lambda functions
|
||||
pynacl==1.5.0 # for encrypting keys
|
||||
pynacl==1.6.2 # for encrypting keys
|
||||
google-cloud-aiplatform==1.47.0 # for vertex ai calls
|
||||
google-cloud-iam==2.19.1 # for GCP IAM Redis authentication
|
||||
google-genai==1.22.0
|
||||
|
|
@ -47,7 +47,7 @@ sentry_sdk==2.21.0 # for sentry error handling
|
|||
detect-secrets==1.5.0 # Enterprise - secret detection / masking in LLM requests
|
||||
cryptography==44.0.1
|
||||
tzdata==2025.1 # IANA time zone database
|
||||
litellm-proxy-extras==0.4.17 # for proxy extras - e.g. prisma migrations
|
||||
litellm-proxy-extras==0.4.18 # for proxy extras - e.g. prisma migrations
|
||||
llm-sandbox==0.3.31 # for skill execution in sandbox
|
||||
### LITELLM PACKAGE DEPENDENCIES
|
||||
python-dotenv==1.0.1 # for env
|
||||
|
|
@ -57,7 +57,7 @@ tokenizers==0.20.2 # for calculating usage
|
|||
click==8.1.7 # for proxy cli
|
||||
rich==13.7.1 # for litellm proxy cli
|
||||
jinja2==3.1.6 # for prompt templates
|
||||
aiohttp==3.12.14 # for network calls
|
||||
aiohttp==3.13.3 # for network calls
|
||||
aioboto3==13.4.0 # for async sagemaker calls
|
||||
tenacity==8.5.0 # for retrying requests, when litellm.num_retries set
|
||||
pydantic>=2.11,<3 # proxy + openai req. + mcp
|
||||
|
|
|
|||
BIN
test_image_edit.png
Normal file
BIN
test_image_edit.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 70 B |
379
tests/code_coverage_tests/check_endpoint_coverage.py
Normal file
379
tests/code_coverage_tests/check_endpoint_coverage.py
Normal file
|
|
@ -0,0 +1,379 @@
|
|||
"""
|
||||
Code coverage test to ensure all endpoints documented in sidebars.js are defined in provider_endpoints_support.json.
|
||||
|
||||
This script:
|
||||
1. Extracts all endpoint entries from the "Supported Endpoints" section of sidebars.js
|
||||
2. Validates that each endpoint has a corresponding entry in the "endpoints" object of provider_endpoints_support.json
|
||||
3. Checks that the "docs_label" field is present in each endpoint definition
|
||||
"""
|
||||
|
||||
import json
|
||||
import re
|
||||
import sys
|
||||
from pathlib import Path
|
||||
from typing import Dict, List, Set, Tuple
|
||||
|
||||
|
||||
class MissingEndpointDefinitionError(Exception):
|
||||
"""Raised when endpoints are documented in sidebars.js but missing from provider_endpoints_support.json."""
|
||||
|
||||
pass
|
||||
|
||||
|
||||
def get_repo_root() -> Path:
|
||||
"""Get the repository root directory."""
|
||||
# Check if litellm directory exists in current working directory
|
||||
cwd = Path.cwd()
|
||||
if (cwd / "litellm").exists() and (cwd / "litellm").is_dir():
|
||||
# We're already at the repo root
|
||||
return cwd
|
||||
|
||||
# Otherwise, navigate up from script location
|
||||
current = Path(__file__).resolve()
|
||||
# Navigate up from tests/code_coverage_tests/
|
||||
return current.parent.parent.parent
|
||||
|
||||
|
||||
def extract_endpoints_from_sidebars() -> Dict[str, str]:
|
||||
"""
|
||||
Extract endpoint entries from sidebars.js.
|
||||
|
||||
Returns a dict mapping endpoint_key -> label
|
||||
Only extracts top-level endpoint entries from the "Supported Endpoints" section.
|
||||
"""
|
||||
repo_root = get_repo_root()
|
||||
sidebars_path = repo_root / "docs" / "my-website" / "sidebars.js"
|
||||
|
||||
if not sidebars_path.exists():
|
||||
print(f"❌ ERROR: Could not find sidebars.js at {sidebars_path}")
|
||||
sys.exit(1)
|
||||
|
||||
with open(sidebars_path, "r") as f:
|
||||
content = f.read()
|
||||
|
||||
# Find the Supported Endpoints section
|
||||
supported_start = content.find('label: "Supported Endpoints"')
|
||||
if supported_start == -1:
|
||||
print("⚠️ WARNING: Could not find 'Supported Endpoints' section")
|
||||
return {}
|
||||
|
||||
# Find the items array within this section
|
||||
items_start = content.find("items: [", supported_start)
|
||||
if items_start == -1:
|
||||
print("⚠️ WARNING: Could not find items array in Supported Endpoints")
|
||||
return {}
|
||||
|
||||
# Find the end of this items array
|
||||
# Look for the closing ], at the same indentation level
|
||||
items_end = content.find("\n ],\n },\n {", items_start)
|
||||
if items_end == -1:
|
||||
items_end = content.find("\n ],\n }", items_start)
|
||||
|
||||
section = content[items_start:items_end]
|
||||
|
||||
endpoints = {}
|
||||
|
||||
# Pattern 1: Categories with labels at the top level (8 spaces indent)
|
||||
# Example: " {type: "category", label: "/a2a - A2A Agent Gateway""
|
||||
category_pattern = (
|
||||
r'^\s{8}\{\s*\n\s{10}type:\s*"category",\s*\n\s{10}label:\s*"([^"]+)"'
|
||||
)
|
||||
for match in re.finditer(category_pattern, section, re.MULTILINE):
|
||||
label = match.group(1)
|
||||
# Skip utility categories
|
||||
if "Pass-through" in label or label == "Vertex AI":
|
||||
continue
|
||||
endpoint_key = label.split(" - ")[0].strip("/").replace("/", "_")
|
||||
endpoints[endpoint_key] = label
|
||||
|
||||
# Pattern 2: Standalone doc strings at top level (8 spaces indent)
|
||||
# Example: " "assistants","
|
||||
standalone_pattern = r'^\s{8}"([a-zA-Z_][a-zA-Z0-9_]*)",?\s*$'
|
||||
for match in re.finditer(standalone_pattern, section, re.MULTILINE):
|
||||
doc_id = match.group(1)
|
||||
endpoints[doc_id] = doc_id
|
||||
|
||||
return endpoints
|
||||
|
||||
|
||||
def load_provider_endpoints_file() -> Dict:
|
||||
"""Load the provider_endpoints_support.json file."""
|
||||
repo_root = get_repo_root()
|
||||
file_path = repo_root / "provider_endpoints_support.json"
|
||||
|
||||
if not file_path.exists():
|
||||
print(
|
||||
f"❌ ERROR: Could not find provider_endpoints_support.json at {file_path}"
|
||||
)
|
||||
sys.exit(1)
|
||||
|
||||
with open(file_path, "r") as f:
|
||||
return json.load(f)
|
||||
|
||||
|
||||
def get_defined_endpoints(data: Dict) -> Dict[str, Dict]:
|
||||
"""Get all endpoint definitions from provider_endpoints_support.json."""
|
||||
return data.get("endpoints", {})
|
||||
|
||||
|
||||
def normalize_endpoint_key(key: str) -> Set[str]:
|
||||
"""
|
||||
Generate variations of an endpoint key for matching.
|
||||
|
||||
Examples:
|
||||
- "a2a" -> {"a2a"}
|
||||
- "chat_completions" -> {"chat_completions", "chatcompletions"}
|
||||
- "vector_stores" -> {"vector_stores", "vectorstores"}
|
||||
"""
|
||||
variations = {key, key.replace("_", "")}
|
||||
return variations
|
||||
|
||||
|
||||
def check_provider_endpoint_keys(data: Dict) -> List[str]:
|
||||
"""
|
||||
Check that all endpoint keys used in providers are defined in the root endpoints section.
|
||||
|
||||
Returns a list of missing endpoint keys.
|
||||
"""
|
||||
# Collect all unique endpoint keys used across all providers
|
||||
provider_endpoint_keys = set()
|
||||
providers = data.get("providers", {})
|
||||
|
||||
for provider_name, provider_data in providers.items():
|
||||
if "endpoints" in provider_data and isinstance(
|
||||
provider_data["endpoints"], dict
|
||||
):
|
||||
provider_endpoint_keys.update(provider_data["endpoints"].keys())
|
||||
|
||||
# Get all endpoint definitions
|
||||
defined_endpoints = data.get("endpoints", {})
|
||||
|
||||
# Collect all provider_json_field values from endpoint definitions
|
||||
provider_json_fields = set()
|
||||
for endpoint_key, endpoint_data in defined_endpoints.items():
|
||||
if isinstance(endpoint_data, dict) and "provider_json_field" in endpoint_data:
|
||||
provider_json_fields.add(endpoint_data["provider_json_field"])
|
||||
|
||||
# Find missing endpoint keys
|
||||
missing_keys = []
|
||||
for key in sorted(provider_endpoint_keys):
|
||||
if key not in provider_json_fields:
|
||||
missing_keys.append(key)
|
||||
|
||||
return missing_keys
|
||||
|
||||
|
||||
def check_unused_endpoints(data: Dict) -> List[Tuple[str, str]]:
|
||||
"""
|
||||
Check that all defined endpoints are used by at least one provider.
|
||||
|
||||
Returns a list of tuples (endpoint_key, provider_json_field) for unused endpoints.
|
||||
"""
|
||||
# Special endpoints that don't need to be used by specific providers
|
||||
# These are utility/framework endpoints available across the platform
|
||||
SPECIAL_ENDPOINTS = {
|
||||
"apply_guardrail", # Guardrail application - works across providers
|
||||
"mcp", # Model Context Protocol - works across providers
|
||||
}
|
||||
|
||||
# Get all endpoint definitions
|
||||
defined_endpoints = data.get("endpoints", {})
|
||||
providers = data.get("providers", {})
|
||||
|
||||
# Collect all endpoint keys used by providers
|
||||
used_keys = set()
|
||||
for provider_data in providers.values():
|
||||
if "endpoints" in provider_data and isinstance(
|
||||
provider_data["endpoints"], dict
|
||||
):
|
||||
used_keys.update(provider_data["endpoints"].keys())
|
||||
|
||||
# Find unused endpoints (excluding special ones)
|
||||
unused = []
|
||||
for endpoint_key, endpoint_data in defined_endpoints.items():
|
||||
# Skip special endpoints
|
||||
if endpoint_key in SPECIAL_ENDPOINTS:
|
||||
continue
|
||||
|
||||
if isinstance(endpoint_data, dict) and "provider_json_field" in endpoint_data:
|
||||
provider_json_field = endpoint_data["provider_json_field"]
|
||||
# Check if this provider_json_field is used by any provider
|
||||
if provider_json_field not in used_keys:
|
||||
unused.append((endpoint_key, provider_json_field))
|
||||
|
||||
return sorted(unused)
|
||||
|
||||
|
||||
def main():
|
||||
"""Main function to validate endpoint coverage."""
|
||||
print(
|
||||
"🔍 Checking endpoint coverage between sidebars.js and provider_endpoints_support.json..."
|
||||
)
|
||||
|
||||
has_errors = False
|
||||
|
||||
# Load provider_endpoints_support.json
|
||||
data = load_provider_endpoints_file()
|
||||
defined_endpoints = get_defined_endpoints(data)
|
||||
|
||||
# Test 1: Check that endpoints from sidebars.js have docs_label entries
|
||||
print("\n📖 Test 1: Checking endpoints from sidebars.js...")
|
||||
sidebar_endpoints = extract_endpoints_from_sidebars()
|
||||
print(f"✓ Found {len(sidebar_endpoints)} endpoints in sidebars.js")
|
||||
print(
|
||||
f"✓ Found {len(defined_endpoints)} endpoint definitions in provider_endpoints_support.json"
|
||||
)
|
||||
|
||||
# Check for missing endpoints
|
||||
missing_endpoints = []
|
||||
|
||||
# Collect all docs_label values from defined endpoints
|
||||
defined_docs_labels = set()
|
||||
for endpoint_data in defined_endpoints.values():
|
||||
if isinstance(endpoint_data, dict) and "docs_label" in endpoint_data:
|
||||
defined_docs_labels.add(endpoint_data["docs_label"])
|
||||
|
||||
for sidebar_key, sidebar_label in sorted(sidebar_endpoints.items()):
|
||||
# Generate variations for matching against docs_label
|
||||
variations = normalize_endpoint_key(sidebar_key)
|
||||
|
||||
# Check if any variation exists in docs_label values
|
||||
if not any(var in defined_docs_labels for var in variations):
|
||||
missing_endpoints.append((sidebar_key, sidebar_label))
|
||||
|
||||
# Report missing endpoints from sidebars
|
||||
if missing_endpoints:
|
||||
has_errors = True
|
||||
error_msg = "\n❌ ERROR: The following endpoints are in sidebars.js but missing from provider_endpoints_support.json:\n"
|
||||
error_msg += "=" * 70 + "\n"
|
||||
|
||||
for key, label in missing_endpoints:
|
||||
error_msg += f" - {key}\n"
|
||||
error_msg += f' Label in sidebars.js: "{label}"\n'
|
||||
|
||||
error_msg += "\n" + "=" * 70 + "\n"
|
||||
error_msg += f"\n💡 To fix: Add these {len(missing_endpoints)} endpoint(s) to the 'endpoints' object\n"
|
||||
error_msg += " in provider_endpoints_support.json\n"
|
||||
error_msg += "\nExample format:\n"
|
||||
error_msg += ' "endpoints": {\n'
|
||||
|
||||
for key, label in missing_endpoints[:5]:
|
||||
error_msg += f' "{key}": {{\n'
|
||||
error_msg += f' "docs_label": "{label}",\n'
|
||||
error_msg += f' "provider_json_field": "{key}",\n'
|
||||
error_msg += f' "description": "Description of the {label} endpoint"\n'
|
||||
error_msg += " },\n"
|
||||
|
||||
if len(missing_endpoints) > 5:
|
||||
error_msg += " ...\n"
|
||||
|
||||
error_msg += " }\n"
|
||||
|
||||
print(error_msg)
|
||||
else:
|
||||
print(
|
||||
f"✅ All {len(sidebar_endpoints)} endpoints from sidebars.js are defined!"
|
||||
)
|
||||
|
||||
# Test 2: Check that all provider endpoint keys have provider_json_field entries
|
||||
print("\n📋 Test 2: Checking provider endpoint keys...")
|
||||
missing_provider_keys = check_provider_endpoint_keys(data)
|
||||
|
||||
if missing_provider_keys:
|
||||
has_errors = True
|
||||
error_msg = "\n❌ ERROR: The following endpoint keys are used in providers but missing provider_json_field definitions:\n"
|
||||
error_msg += "=" * 70 + "\n"
|
||||
|
||||
for key in missing_provider_keys:
|
||||
# Find which providers use this key
|
||||
using_providers = []
|
||||
for provider_name, provider_data in data.get("providers", {}).items():
|
||||
if key in provider_data.get("endpoints", {}):
|
||||
using_providers.append(provider_name)
|
||||
|
||||
error_msg += f" - {key}\n"
|
||||
error_msg += f" Used by {len(using_providers)} provider(s): {', '.join(using_providers[:3])}"
|
||||
if len(using_providers) > 3:
|
||||
error_msg += f" and {len(using_providers) - 3} more"
|
||||
error_msg += "\n"
|
||||
|
||||
error_msg += "\n" + "=" * 70 + "\n"
|
||||
error_msg += f"\n💡 To fix: Add these {len(missing_provider_keys)} endpoint(s) to the 'endpoints' object\n"
|
||||
error_msg += " in provider_endpoints_support.json with 'provider_json_field' matching the key\n"
|
||||
error_msg += "\nExample format:\n"
|
||||
error_msg += ' "endpoints": {\n'
|
||||
|
||||
for key in missing_provider_keys[:3]:
|
||||
error_msg += f' "{key}": {{\n'
|
||||
error_msg += f' "docs_label": "{key}",\n'
|
||||
error_msg += f' "provider_json_field": "{key}",\n'
|
||||
error_msg += f' "description": "Description of the {key} endpoint"\n'
|
||||
error_msg += " },\n"
|
||||
|
||||
if len(missing_provider_keys) > 3:
|
||||
error_msg += " ...\n"
|
||||
|
||||
error_msg += " }\n"
|
||||
|
||||
print(error_msg)
|
||||
else:
|
||||
print("✅ All provider endpoint keys have provider_json_field definitions!")
|
||||
|
||||
# Test 3: Check that all defined endpoints are used by at least one provider
|
||||
print("\n🔍 Test 3: Checking for unused endpoint definitions...")
|
||||
unused_endpoints = check_unused_endpoints(data)
|
||||
|
||||
if unused_endpoints:
|
||||
has_errors = True
|
||||
error_msg = "\n⚠️ WARNING: The following endpoint definitions are not used by any provider:\n"
|
||||
error_msg += "=" * 70 + "\n"
|
||||
|
||||
for endpoint_key, provider_json_field in unused_endpoints:
|
||||
endpoint_data = defined_endpoints.get(endpoint_key, {})
|
||||
docs_label = endpoint_data.get("docs_label", "N/A")
|
||||
error_msg += f" - {endpoint_key}\n"
|
||||
error_msg += f" provider_json_field: '{provider_json_field}'\n"
|
||||
error_msg += f" docs_label: '{docs_label}'\n"
|
||||
|
||||
error_msg += "\n" + "=" * 70 + "\n"
|
||||
error_msg += f"\n💡 These {len(unused_endpoints)} endpoint(s) are defined but not used by any provider.\n"
|
||||
error_msg += " Either:\n"
|
||||
error_msg += (
|
||||
" 1. Add the endpoint to relevant providers' 'endpoints' objects, OR\n"
|
||||
)
|
||||
error_msg += " 2. Remove the endpoint definition if it's no longer needed\n"
|
||||
|
||||
print(error_msg)
|
||||
else:
|
||||
print("✅ All endpoint definitions are used by at least one provider!")
|
||||
|
||||
# Raise error if any tests failed
|
||||
if has_errors:
|
||||
error_summary = []
|
||||
if missing_endpoints:
|
||||
error_summary.append(f"{len(missing_endpoints)} endpoints from sidebars.js")
|
||||
if missing_provider_keys:
|
||||
error_summary.append(f"{len(missing_provider_keys)} provider endpoint keys")
|
||||
if unused_endpoints:
|
||||
error_summary.append(f"{len(unused_endpoints)} unused endpoint definitions")
|
||||
|
||||
raise MissingEndpointDefinitionError(
|
||||
f"Endpoint validation failed: Missing definitions for {' and '.join(error_summary)}"
|
||||
)
|
||||
|
||||
print("\n🎉 All endpoint coverage validations passed!")
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
try:
|
||||
sys.exit(main())
|
||||
except MissingEndpointDefinitionError as e:
|
||||
print(f"\n🚨 CRITICAL ERROR: {e}\n")
|
||||
sys.exit(1)
|
||||
except Exception as e:
|
||||
print(f"\n🚨 UNEXPECTED ERROR: {e}\n")
|
||||
import traceback
|
||||
|
||||
traceback.print_exc()
|
||||
sys.exit(1)
|
||||
294
tests/code_coverage_tests/check_provider_folders_documented.py
Normal file
294
tests/code_coverage_tests/check_provider_folders_documented.py
Normal file
|
|
@ -0,0 +1,294 @@
|
|||
"""
|
||||
Code coverage test to ensure all provider folders are documented.
|
||||
|
||||
This script validates that:
|
||||
1. Every provider folder in litellm/llms/ has a corresponding entry in provider_endpoints_support.json
|
||||
2. Every provider in litellm/llms/openai_like/providers.json is documented in provider_endpoints_support.json
|
||||
"""
|
||||
|
||||
import json
|
||||
import os
|
||||
import sys
|
||||
from pathlib import Path
|
||||
from typing import Dict, List, Set, Tuple
|
||||
|
||||
|
||||
class UndocumentedProviderError(Exception):
|
||||
"""Raised when providers are found without documentation."""
|
||||
|
||||
pass
|
||||
|
||||
|
||||
# Special folders that should be excluded from validation
|
||||
EXCLUDED_FOLDERS = {
|
||||
"__pycache__",
|
||||
"base_llm",
|
||||
"deprecated_providers",
|
||||
"custom_httpx",
|
||||
"pass_through",
|
||||
"openai_like", # This is a generic handler, not a specific provider
|
||||
"aiohttp_openai", # Internal implementation detail for async HTTP
|
||||
}
|
||||
|
||||
|
||||
def get_repo_root() -> Path:
|
||||
"""Get the repository root directory."""
|
||||
# Check if litellm directory exists in current working directory
|
||||
cwd = Path.cwd()
|
||||
if (cwd / "litellm").exists() and (cwd / "litellm").is_dir():
|
||||
# We're already at the repo root
|
||||
return cwd
|
||||
|
||||
# Otherwise, navigate up from script location
|
||||
current = Path(__file__).resolve()
|
||||
# Navigate up from tests/code_coverage_tests/
|
||||
return current.parent.parent.parent
|
||||
|
||||
|
||||
def get_llm_provider_folders() -> Set[str]:
|
||||
"""Get all provider folder names from litellm/llms directory."""
|
||||
repo_root = get_repo_root()
|
||||
llms_dir = repo_root / "litellm" / "llms"
|
||||
|
||||
if not llms_dir.exists():
|
||||
print(f"❌ ERROR: Could not find llms directory at {llms_dir}")
|
||||
sys.exit(1)
|
||||
|
||||
folders = set()
|
||||
for item in llms_dir.iterdir():
|
||||
if item.is_dir() and item.name not in EXCLUDED_FOLDERS:
|
||||
folders.add(item.name)
|
||||
|
||||
return folders
|
||||
|
||||
|
||||
def load_provider_endpoints_file() -> Dict:
|
||||
"""Load the provider_endpoints_support.json file."""
|
||||
repo_root = get_repo_root()
|
||||
file_path = repo_root / "provider_endpoints_support.json"
|
||||
|
||||
if not file_path.exists():
|
||||
print(
|
||||
f"❌ ERROR: Could not find provider_endpoints_support.json at {file_path}"
|
||||
)
|
||||
sys.exit(1)
|
||||
|
||||
with open(file_path, "r") as f:
|
||||
return json.load(f)
|
||||
|
||||
|
||||
def get_openai_like_providers() -> Set[str]:
|
||||
"""Get all provider names from litellm/llms/openai_like/providers.json."""
|
||||
repo_root = get_repo_root()
|
||||
providers_file = repo_root / "litellm" / "llms" / "openai_like" / "providers.json"
|
||||
|
||||
if not providers_file.exists():
|
||||
print(
|
||||
f"⚠️ WARNING: Could not find openai_like/providers.json at {providers_file}"
|
||||
)
|
||||
return set()
|
||||
|
||||
with open(providers_file, "r") as f:
|
||||
data = json.load(f)
|
||||
|
||||
# Return all provider keys from the JSON
|
||||
return set(data.keys())
|
||||
|
||||
|
||||
def get_documented_providers(data: Dict) -> Set[str]:
|
||||
"""Get all provider slugs documented in provider_endpoints_support.json."""
|
||||
providers = data.get("providers", {})
|
||||
|
||||
# Get all provider keys, including those with slashes
|
||||
documented = set()
|
||||
for provider_key in providers.keys():
|
||||
# For providers like "azure_ai/doc-intelligence", extract base name
|
||||
base_name = provider_key.split("/")[0]
|
||||
documented.add(base_name)
|
||||
# Also add the full key in case folder name matches exactly
|
||||
documented.add(provider_key)
|
||||
|
||||
return documented
|
||||
|
||||
|
||||
def normalize_provider_name(folder_name: str) -> Set[str]:
|
||||
"""
|
||||
Generate possible provider names that might match a folder.
|
||||
|
||||
Some folders might have variations in the JSON:
|
||||
- github_copilot folder -> github_copilot provider
|
||||
- azure folder -> azure, azure_text, azure_ai providers
|
||||
"""
|
||||
variations = {folder_name}
|
||||
|
||||
# Add common variations
|
||||
if "_" in folder_name:
|
||||
# Try without underscores (though less common)
|
||||
variations.add(folder_name.replace("_", ""))
|
||||
|
||||
return variations
|
||||
|
||||
|
||||
def main():
|
||||
"""Main function to validate provider documentation."""
|
||||
print("🔍 Checking that all providers are documented...")
|
||||
|
||||
has_errors = False
|
||||
|
||||
# Check 1: Provider folders in litellm/llms
|
||||
print("\n📁 Checking provider folders in litellm/llms/...")
|
||||
provider_folders = get_llm_provider_folders()
|
||||
print(f"✓ Found {len(provider_folders)} provider folders")
|
||||
|
||||
# Check 2: OpenAI-like providers
|
||||
print("\n📋 Checking openai_like providers...")
|
||||
openai_like_providers = get_openai_like_providers()
|
||||
print(f"✓ Found {len(openai_like_providers)} openai_like providers")
|
||||
|
||||
# Load the JSON file
|
||||
data = load_provider_endpoints_file()
|
||||
documented_providers = get_documented_providers(data)
|
||||
print(
|
||||
f"\n✓ Found {len(data.get('providers', {}))} provider entries in provider_endpoints_support.json"
|
||||
)
|
||||
|
||||
# Check for undocumented folders
|
||||
undocumented_folders = []
|
||||
for folder in sorted(provider_folders):
|
||||
# Check if folder name or any variation is documented
|
||||
variations = normalize_provider_name(folder)
|
||||
if not any(var in documented_providers for var in variations):
|
||||
undocumented_folders.append(folder)
|
||||
|
||||
# Check for undocumented openai_like providers
|
||||
undocumented_openai_like = []
|
||||
for provider in sorted(openai_like_providers):
|
||||
# Generate multiple possible variations of the provider name
|
||||
variations = {
|
||||
provider, # Original name (e.g., "nano-gpt")
|
||||
provider.replace(
|
||||
"-", "_"
|
||||
), # Replace hyphens with underscores (e.g., "nano_gpt")
|
||||
provider.replace("-", ""), # Remove hyphens (e.g., "nanogpt")
|
||||
provider.replace("_", ""), # Remove underscores
|
||||
}
|
||||
|
||||
# Special case mappings for known variations
|
||||
special_mappings = {
|
||||
"veniceai": "venice",
|
||||
"nano-gpt": "nanogpt",
|
||||
}
|
||||
if provider in special_mappings:
|
||||
variations.add(special_mappings[provider])
|
||||
|
||||
# Check if any variation is documented
|
||||
if not any(var in documented_providers for var in variations):
|
||||
undocumented_openai_like.append(provider)
|
||||
|
||||
# Collect all error messages
|
||||
error_messages: List[str] = []
|
||||
|
||||
# Report errors for undocumented folders
|
||||
if undocumented_folders:
|
||||
has_errors = True
|
||||
error_msg = "\n❌ ERROR: The following provider folders are not documented:\n"
|
||||
error_msg += "=" * 70 + "\n"
|
||||
for folder in undocumented_folders:
|
||||
error_msg += f" - litellm/llms/{folder}/\n"
|
||||
|
||||
error_msg += "\n" + "=" * 70 + "\n"
|
||||
error_msg += f"\n💡 To fix: Add entries for these {len(undocumented_folders)} provider(s)\n"
|
||||
error_msg += (
|
||||
" in the 'providers' section of provider_endpoints_support.json\n"
|
||||
)
|
||||
error_msg += "\nExample format:\n"
|
||||
error_msg += ' "providers": {\n'
|
||||
for folder in undocumented_folders[:3]:
|
||||
error_msg += f' "{folder}": {{\n'
|
||||
error_msg += f' "display_name": "{folder.replace("_", " ").title()} (`{folder}`)",\n'
|
||||
error_msg += (
|
||||
f' "url": "https://docs.litellm.ai/docs/providers/{folder}",\n'
|
||||
)
|
||||
error_msg += ' "endpoints": {\n'
|
||||
error_msg += ' "chat_completions": true,\n'
|
||||
error_msg += ' "messages": true,\n'
|
||||
error_msg += ' "responses": true,\n'
|
||||
error_msg += ' "embeddings": false,\n'
|
||||
error_msg += " ...\n"
|
||||
error_msg += " }\n"
|
||||
error_msg += " },\n"
|
||||
if len(undocumented_folders) > 3:
|
||||
error_msg += " ...\n"
|
||||
error_msg += " }\n"
|
||||
|
||||
print(error_msg)
|
||||
error_messages.append(
|
||||
f"Found {len(undocumented_folders)} undocumented provider folders: {', '.join(undocumented_folders)}"
|
||||
)
|
||||
|
||||
# Report errors for undocumented openai_like providers
|
||||
if undocumented_openai_like:
|
||||
has_errors = True
|
||||
error_msg = (
|
||||
"\n❌ ERROR: The following openai_like providers are not documented:\n"
|
||||
)
|
||||
error_msg += "=" * 70 + "\n"
|
||||
for provider in undocumented_openai_like:
|
||||
error_msg += f" - {provider}\n"
|
||||
|
||||
error_msg += "\n" + "=" * 70 + "\n"
|
||||
error_msg += f"\n💡 To fix: Add entries for these {len(undocumented_openai_like)} provider(s)\n"
|
||||
error_msg += (
|
||||
" in the 'providers' section of provider_endpoints_support.json\n"
|
||||
)
|
||||
error_msg += "\nExample format:\n"
|
||||
error_msg += ' "providers": {\n'
|
||||
for provider in undocumented_openai_like[:3]:
|
||||
normalized = provider.replace("-", "_")
|
||||
error_msg += f' "{normalized}": {{\n'
|
||||
error_msg += f' "display_name": "{provider.replace("-", " ").replace("_", " ").title()} (`{normalized}`)",\n'
|
||||
error_msg += (
|
||||
f' "url": "https://docs.litellm.ai/docs/providers/{normalized}",\n'
|
||||
)
|
||||
error_msg += ' "endpoints": {\n'
|
||||
error_msg += ' "chat_completions": true,\n'
|
||||
error_msg += ' "messages": true,\n'
|
||||
error_msg += ' "responses": true,\n'
|
||||
error_msg += ' "embeddings": false,\n'
|
||||
error_msg += " ...\n"
|
||||
error_msg += " }\n"
|
||||
error_msg += " },\n"
|
||||
if len(undocumented_openai_like) > 3:
|
||||
error_msg += " ...\n"
|
||||
error_msg += " }\n"
|
||||
|
||||
print(error_msg)
|
||||
error_messages.append(
|
||||
f"Found {len(undocumented_openai_like)} undocumented openai_like providers: {', '.join(undocumented_openai_like)}"
|
||||
)
|
||||
|
||||
# Raise exception if there are any errors
|
||||
if has_errors:
|
||||
error_summary = " AND ".join(error_messages)
|
||||
raise UndocumentedProviderError(
|
||||
f"Provider documentation validation failed: {error_summary}"
|
||||
)
|
||||
|
||||
print(f"\n✅ All {len(provider_folders)} provider folders are documented!")
|
||||
print(f"✅ All {len(openai_like_providers)} openai_like providers are documented!")
|
||||
print("\n🎉 All provider documentation checks passed!")
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
try:
|
||||
sys.exit(main())
|
||||
except UndocumentedProviderError as e:
|
||||
print(f"\n🚨 CRITICAL ERROR: {e}\n")
|
||||
sys.exit(1)
|
||||
except Exception as e:
|
||||
print(f"\n🚨 UNEXPECTED ERROR: {e}\n")
|
||||
import traceback
|
||||
|
||||
traceback.print_exc()
|
||||
sys.exit(1)
|
||||
|
|
@ -138,4 +138,5 @@ pondpond: >=1.4.1 # Apache 2.0 License
|
|||
fastuuid: >=0.13.0 # BSD-3-Clause license
|
||||
llm-sandbox: >=0.3.31 # MIT License - https://github.com/vndee/llm-sandbox
|
||||
nodejs-wheel-binaries: >=24.12.0 # MIT license manually verified
|
||||
grpcio: >=1.69.0 # Apache License 2.0
|
||||
|
||||
|
|
|
|||
|
|
@ -143,6 +143,23 @@ class TestOpenAIImageEditDallE2(BaseLLMImageEditTest):
|
|||
}
|
||||
|
||||
|
||||
class TestAzureAIFlux2ImageEdit(BaseLLMImageEditTest):
|
||||
"""
|
||||
Concrete implementation of BaseLLMImageEditTest for Azure AI FLUX 2 image edits.
|
||||
FLUX 2 uses JSON with base64 image instead of multipart/form-data.
|
||||
"""
|
||||
|
||||
def get_base_image_edit_call_args(self) -> dict:
|
||||
"""Return base call args for Azure AI FLUX 2 image edit"""
|
||||
return {
|
||||
"model": "azure_ai/flux.2-pro",
|
||||
"image": SINGLE_TEST_IMAGE,
|
||||
"api_base": os.getenv("AZURE_AI_API_BASE", "https://litellm-ci-cd-prod.services.ai.azure.com"),
|
||||
"api_key": os.getenv("AZURE_AI_API_KEY"),
|
||||
"api_version": "preview",
|
||||
}
|
||||
|
||||
|
||||
@pytest.mark.flaky(retries=3, delay=2)
|
||||
@pytest.mark.asyncio
|
||||
async def test_openai_image_edit_litellm_router():
|
||||
|
|
@ -322,14 +339,23 @@ async def test_openai_image_edit_cost_tracking():
|
|||
litellm.logging_callback_manager._reset_all_callbacks()
|
||||
litellm.callbacks = [test_custom_logger]
|
||||
|
||||
# Mock response for Azure image edit
|
||||
# Mock response for Azure image edit with usage data for cost tracking
|
||||
mock_response = {
|
||||
"created": 1589478378,
|
||||
"data": [
|
||||
{
|
||||
"b64_json": "iVBORw0KGgoAAAANSUhEUgAAAAEAAAABCAYAAAAfFcSJAAAADUlEQVR42mP8/5+hHgAHggJ/PchI7wAAAABJRU5ErkJggg=="
|
||||
}
|
||||
]
|
||||
],
|
||||
"usage": {
|
||||
"total_tokens": 1100,
|
||||
"input_tokens": 100,
|
||||
"input_tokens_details": {
|
||||
"image_tokens": 50,
|
||||
"text_tokens": 50
|
||||
},
|
||||
"output_tokens": 1000
|
||||
}
|
||||
}
|
||||
|
||||
class MockResponse:
|
||||
|
|
@ -401,14 +427,23 @@ async def test_azure_image_edit_cost_tracking():
|
|||
litellm.logging_callback_manager._reset_all_callbacks()
|
||||
litellm.callbacks = [test_custom_logger]
|
||||
|
||||
# Mock response for Azure image edit
|
||||
# Mock response for Azure image edit with usage data for cost tracking
|
||||
mock_response = {
|
||||
"created": 1589478378,
|
||||
"data": [
|
||||
{
|
||||
"b64_json": "iVBORw0KGgoAAAANSUhEUgAAAAEAAAABCAYAAAAfFcSJAAAADUlEQVR42mP8/5+hHgAHggJ/PchI7wAAAABJRU5ErkJggg=="
|
||||
}
|
||||
]
|
||||
],
|
||||
"usage": {
|
||||
"total_tokens": 1100,
|
||||
"input_tokens": 100,
|
||||
"input_tokens_details": {
|
||||
"image_tokens": 50,
|
||||
"text_tokens": 50
|
||||
},
|
||||
"output_tokens": 1000
|
||||
}
|
||||
}
|
||||
|
||||
class MockResponse:
|
||||
|
|
|
|||
|
|
@ -322,10 +322,7 @@ def process_stream_response(res, messages):
|
|||
return res
|
||||
|
||||
|
||||
@pytest.mark.skipif(
|
||||
os.environ.get("CIRCLE_OIDC_TOKEN_V2") is None,
|
||||
reason="Cannot run without being in CircleCI Runner",
|
||||
)
|
||||
@pytest.mark.skip(reason="Cannot run without being in CircleCI Runner")
|
||||
def test_completion_bedrock_claude_aws_session_token(bedrock_session_token_creds):
|
||||
print("\ncalling bedrock claude with aws_session_token auth")
|
||||
|
||||
|
|
@ -406,10 +403,7 @@ def test_completion_bedrock_claude_aws_session_token(bedrock_session_token_creds
|
|||
pytest.fail(f"Error occurred: {e}")
|
||||
|
||||
|
||||
@pytest.mark.skipif(
|
||||
os.environ.get("CIRCLE_OIDC_TOKEN_V2") is None,
|
||||
reason="Cannot run without being in CircleCI Runner",
|
||||
)
|
||||
@pytest.mark.skip(reason="Cannot run without being in CircleCI Runner")
|
||||
def test_completion_bedrock_claude_aws_bedrock_client(bedrock_session_token_creds):
|
||||
print("\ncalling bedrock claude with aws_session_token auth")
|
||||
|
||||
|
|
|
|||
|
|
@ -71,6 +71,7 @@ def test_get_arize_config(mock_env_vars):
|
|||
assert config.api_key == "test_api_key"
|
||||
assert config.endpoint == "https://otlp.arize.com/v1"
|
||||
assert config.protocol == "otlp_grpc"
|
||||
assert config.project_name is None
|
||||
|
||||
|
||||
def test_get_arize_config_with_endpoints(mock_env_vars, monkeypatch):
|
||||
|
|
@ -79,10 +80,12 @@ def test_get_arize_config_with_endpoints(mock_env_vars, monkeypatch):
|
|||
"""
|
||||
monkeypatch.setenv("ARIZE_ENDPOINT", "grpc://test.endpoint")
|
||||
monkeypatch.setenv("ARIZE_HTTP_ENDPOINT", "http://test.endpoint")
|
||||
monkeypatch.setenv("ARIZE_PROJECT_NAME", "custom-project")
|
||||
|
||||
config = ArizeLogger.get_arize_config()
|
||||
assert config.endpoint == "grpc://test.endpoint"
|
||||
assert config.protocol == "otlp_grpc"
|
||||
assert config.project_name == "custom-project"
|
||||
|
||||
|
||||
@pytest.mark.skip(
|
||||
|
|
|
|||
|
|
@ -3059,7 +3059,6 @@ def response_format_tests(response: litellm.ModelResponse):
|
|||
"bedrock/cohere.command-r-plus-v1:0",
|
||||
"anthropic.claude-3-sonnet-20240229-v1:0",
|
||||
"mistral.mistral-7b-instruct-v0:2",
|
||||
# "bedrock/amazon.titan-tg1-large",
|
||||
"meta.llama3-8b-instruct-v1:0",
|
||||
],
|
||||
)
|
||||
|
|
@ -3101,31 +3100,6 @@ async def test_completion_bedrock_httpx_models(sync_mode, model):
|
|||
pytest.fail(f"An error occurred - {str(e)}")
|
||||
|
||||
|
||||
def test_completion_bedrock_titan_null_response():
|
||||
try:
|
||||
# amazon.titan-text-lite-v1 is deprecated, using titan-text-express-v1 instead
|
||||
response = completion(
|
||||
model="bedrock/amazon.titan-text-express-v1",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Hello!",
|
||||
},
|
||||
{
|
||||
"role": "assistant",
|
||||
"content": "Hello! How can I help you?",
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What model are you?",
|
||||
},
|
||||
],
|
||||
)
|
||||
# Add any assertions here to check the response
|
||||
print(f"response: {response}")
|
||||
except Exception as e:
|
||||
pytest.fail(f"An error occurred - {str(e)}")
|
||||
|
||||
|
||||
# test_completion_bedrock_titan()
|
||||
|
||||
|
|
@ -3916,26 +3890,7 @@ async def test_dynamic_azure_params(stream, sync_mode):
|
|||
raise e
|
||||
|
||||
|
||||
@pytest.mark.asyncio()
|
||||
@pytest.mark.flaky(retries=3, delay=1)
|
||||
async def test_completion_ai21_chat():
|
||||
litellm.set_verbose = True
|
||||
try:
|
||||
response = await litellm.acompletion(
|
||||
model="ai21_chat/jamba-mini",
|
||||
user="ishaan",
|
||||
tool_choice="auto",
|
||||
seed=123,
|
||||
messages=[{"role": "user", "content": "what does the document say"}],
|
||||
documents=[
|
||||
{
|
||||
"content": "hello world",
|
||||
"metadata": {"source": "google", "author": "ishaan"},
|
||||
}
|
||||
],
|
||||
)
|
||||
except litellm.InternalServerError:
|
||||
pytest.skip("Model is overloaded")
|
||||
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
|
|
|
|||
|
|
@ -552,36 +552,6 @@ async def test_completion_predibase_streaming(sync_mode):
|
|||
pytest.fail(f"Error occurred: {e}")
|
||||
|
||||
|
||||
@pytest.mark.asyncio()
|
||||
@pytest.mark.flaky(retries=3, delay=1)
|
||||
async def test_completion_ai21_stream():
|
||||
litellm.set_verbose = True
|
||||
response = await litellm.acompletion(
|
||||
model="ai21_chat/jamba-mini",
|
||||
user="ishaan",
|
||||
stream=True,
|
||||
seed=123,
|
||||
messages=[{"role": "user", "content": "hi my name is ishaan"}],
|
||||
)
|
||||
complete_response = ""
|
||||
idx = 0
|
||||
async for init_chunk in response:
|
||||
chunk, finished = streaming_format_tests(idx, init_chunk)
|
||||
complete_response += chunk
|
||||
custom_llm_provider = init_chunk._hidden_params["custom_llm_provider"]
|
||||
print(f"custom_llm_provider: {custom_llm_provider}")
|
||||
assert custom_llm_provider == "ai21_chat"
|
||||
idx += 1
|
||||
if finished:
|
||||
assert isinstance(init_chunk.choices[0], litellm.utils.StreamingChoices)
|
||||
break
|
||||
if complete_response.strip() == "":
|
||||
raise Exception("Empty response received")
|
||||
|
||||
print(f"complete_response: {complete_response}")
|
||||
|
||||
pass
|
||||
|
||||
|
||||
def test_completion_azure_function_calling_stream():
|
||||
try:
|
||||
|
|
@ -1318,7 +1288,6 @@ async def test_completion_replicate_llama3_streaming(sync_mode):
|
|||
# ["bedrock/cohere.command-r-plus-v1:0", None],
|
||||
["anthropic.claude-3-sonnet-20240229-v1:0", None],
|
||||
# ["mistral.mistral-7b-instruct-v0:2", None],
|
||||
["bedrock/amazon.titan-tg1-large", None],
|
||||
# ["meta.llama3-8b-instruct-v1:0", None],
|
||||
],
|
||||
)
|
||||
|
|
|
|||
|
|
@ -40,6 +40,7 @@ ignored_keys = [
|
|||
"metadata.usage_object",
|
||||
"metadata.cold_storage_object_key",
|
||||
"metadata.litellm_overhead_time_ms",
|
||||
"metadata.cost_breakdown",
|
||||
]
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -138,64 +138,6 @@ def validate_raw_gen_ai_request_openai_streaming(span):
|
|||
assert span._attributes[attr] is not None, f"Attribute {attr} has None"
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"model",
|
||||
["anthropic/claude-3-opus-20240229"],
|
||||
)
|
||||
@pytest.mark.flaky(retries=6, delay=2)
|
||||
def test_completion_claude_3_function_call_with_otel(model):
|
||||
litellm.set_verbose = True
|
||||
|
||||
litellm.callbacks = [OpenTelemetry(config=OpenTelemetryConfig(exporter=exporter))]
|
||||
tools = [
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_current_weather",
|
||||
"description": "Get the current weather in a given location",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {
|
||||
"type": "string",
|
||||
"description": "The city and state, e.g. San Francisco, CA",
|
||||
},
|
||||
"unit": {"type": "string", "enum": ["celsius", "fahrenheit"]},
|
||||
},
|
||||
"required": ["location"],
|
||||
},
|
||||
},
|
||||
}
|
||||
]
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What's the weather like in Boston today in Fahrenheit?",
|
||||
}
|
||||
]
|
||||
try:
|
||||
# test without max tokens
|
||||
response = litellm.completion(
|
||||
model=model,
|
||||
messages=messages,
|
||||
tools=tools,
|
||||
tool_choice={
|
||||
"type": "function",
|
||||
"function": {"name": "get_current_weather"},
|
||||
},
|
||||
drop_params=True,
|
||||
)
|
||||
|
||||
print("response from LiteLLM", response)
|
||||
except litellm.InternalServerError:
|
||||
pass
|
||||
except Exception as e:
|
||||
pytest.fail(f"Error occurred: {e}")
|
||||
finally:
|
||||
# clear in memory exporter
|
||||
exporter.clear()
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
@pytest.mark.parametrize("streaming", [True, False])
|
||||
@pytest.mark.parametrize("global_redact", [True, False])
|
||||
|
|
|
|||
|
|
@ -21,7 +21,7 @@ class TestAnthropicMessagesEndpoint(BaseAnthropicMessagesTest):
|
|||
def test_anthropic_messages_to_wildcard_model(self):
|
||||
client = self.get_client()
|
||||
response = client.messages.create(
|
||||
model="anthropic/claude-3-opus-20240229",
|
||||
model="anthropic/claude-haiku-4-5-20251001",
|
||||
messages=[{"role": "user", "content": "Hello, world!"}],
|
||||
max_tokens=100,
|
||||
)
|
||||
|
|
|
|||
|
|
@ -3504,6 +3504,7 @@ async def test_list_keys(prisma_client):
|
|||
include_created_by_keys=False,
|
||||
sort_by=None,
|
||||
sort_order="desc",
|
||||
expand=None,
|
||||
)
|
||||
print("response=", response)
|
||||
assert "keys" in response
|
||||
|
|
@ -3528,6 +3529,7 @@ async def test_list_keys(prisma_client):
|
|||
include_created_by_keys=False,
|
||||
sort_by=None,
|
||||
sort_order="desc",
|
||||
expand=None,
|
||||
)
|
||||
print("pagination response=", response)
|
||||
assert len(response["keys"]) == 2
|
||||
|
|
@ -3568,6 +3570,7 @@ async def test_list_keys(prisma_client):
|
|||
include_created_by_keys=False,
|
||||
sort_by=None,
|
||||
sort_order="desc",
|
||||
expand=None,
|
||||
)
|
||||
print("filtered user_id response=", response)
|
||||
assert len(response["keys"]) == 1
|
||||
|
|
@ -3589,6 +3592,7 @@ async def test_list_keys(prisma_client):
|
|||
include_created_by_keys=False,
|
||||
sort_by=None,
|
||||
sort_order="desc",
|
||||
expand=None,
|
||||
)
|
||||
assert len(response["keys"]) == 1
|
||||
assert _key in response["keys"]
|
||||
|
|
|
|||
|
|
@ -73,7 +73,7 @@ def test_routing_strategy_init(model_list):
|
|||
from litellm.types.router import RoutingStrategy
|
||||
|
||||
router = Router(model_list=model_list)
|
||||
for strategy in RoutingStrategy._member_names_:
|
||||
for strategy in RoutingStrategy:
|
||||
router.routing_strategy_init(
|
||||
routing_strategy=strategy, routing_strategy_args={}
|
||||
)
|
||||
|
|
|
|||
|
|
@ -134,80 +134,6 @@ class TestContainerAPI:
|
|||
assert response.id == "cntr_async_123"
|
||||
assert response.name == "Async Test Container"
|
||||
|
||||
def test_list_containers_basic(self):
|
||||
"""Test basic container listing functionality."""
|
||||
mock_response = ContainerListResponse(
|
||||
object="list",
|
||||
data=[
|
||||
ContainerObject(
|
||||
id="cntr_1",
|
||||
object="container",
|
||||
created_at=1747857508,
|
||||
status="running",
|
||||
expires_after={"anchor": "last_active_at", "minutes": 20},
|
||||
last_active_at=1747857508,
|
||||
name="Container 1"
|
||||
),
|
||||
ContainerObject(
|
||||
id="cntr_2",
|
||||
object="container",
|
||||
created_at=1747857600,
|
||||
status="running",
|
||||
expires_after={"anchor": "last_active_at", "minutes": 15},
|
||||
last_active_at=1747857600,
|
||||
name="Container 2"
|
||||
)
|
||||
],
|
||||
first_id="cntr_1",
|
||||
last_id="cntr_2",
|
||||
has_more=False
|
||||
)
|
||||
|
||||
with patch('litellm.containers.main.base_llm_http_handler') as mock_handler:
|
||||
mock_handler.container_list_handler.return_value = mock_response
|
||||
|
||||
response = list_containers(
|
||||
custom_llm_provider="openai"
|
||||
)
|
||||
|
||||
assert isinstance(response, ContainerListResponse)
|
||||
assert len(response.data) == 2
|
||||
assert response.data[0].id == "cntr_1"
|
||||
assert response.data[1].id == "cntr_2"
|
||||
assert response.has_more == False
|
||||
|
||||
def test_list_containers_with_params(self):
|
||||
"""Test container listing with parameters."""
|
||||
mock_response = ContainerListResponse(
|
||||
object="list",
|
||||
data=[
|
||||
ContainerObject(
|
||||
id="cntr_limited",
|
||||
object="container",
|
||||
created_at=1747857508,
|
||||
status="running",
|
||||
expires_after={"anchor": "last_active_at", "minutes": 20},
|
||||
last_active_at=1747857508,
|
||||
name="Limited Container"
|
||||
)
|
||||
],
|
||||
first_id="cntr_limited",
|
||||
last_id="cntr_limited",
|
||||
has_more=True
|
||||
)
|
||||
|
||||
with patch('litellm.containers.main.base_llm_http_handler') as mock_handler:
|
||||
mock_handler.container_list_handler.return_value = mock_response
|
||||
|
||||
response = list_containers(
|
||||
limit=1,
|
||||
order="desc",
|
||||
after="cntr_prev",
|
||||
custom_llm_provider="openai"
|
||||
)
|
||||
|
||||
assert len(response.data) == 1
|
||||
assert response.has_more == True
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_alist_containers_basic(self):
|
||||
|
|
|
|||
|
|
@ -123,7 +123,8 @@ class TestArizeIntegrationWithProxy:
|
|||
with patch.dict(os.environ, {
|
||||
"ARIZE_SPACE_KEY": "test-space-123",
|
||||
"ARIZE_API_KEY": "test-api-456",
|
||||
"ARIZE_ENDPOINT": "https://custom.arize.com/v1"
|
||||
"ARIZE_ENDPOINT": "https://custom.arize.com/v1",
|
||||
"ARIZE_PROJECT_NAME": "custom-project",
|
||||
}):
|
||||
config = ArizeLogger.get_arize_config()
|
||||
|
||||
|
|
@ -131,13 +132,15 @@ class TestArizeIntegrationWithProxy:
|
|||
assert config.api_key == "test-api-456"
|
||||
assert config.endpoint == "https://custom.arize.com/v1"
|
||||
assert config.protocol == "otlp_grpc"
|
||||
assert config.project_name == "custom-project"
|
||||
|
||||
def test_arize_get_config_defaults(self):
|
||||
"""Test ArizeLogger.get_arize_config() with default endpoint."""
|
||||
|
||||
with patch.dict(os.environ, {
|
||||
"ARIZE_SPACE_KEY": "test-space-default",
|
||||
"ARIZE_API_KEY": "test-api-default"
|
||||
"ARIZE_API_KEY": "test-api-default",
|
||||
"ARIZE_PROJECT_NAME": "default-project",
|
||||
}, clear=True):
|
||||
config = ArizeLogger.get_arize_config()
|
||||
|
||||
|
|
@ -145,6 +148,7 @@ class TestArizeIntegrationWithProxy:
|
|||
assert config.api_key == "test-api-default"
|
||||
assert config.endpoint == "https://otlp.arize.com/v1" # Default endpoint
|
||||
assert config.protocol == "otlp_grpc" # Default protocol
|
||||
assert config.project_name == "default-project"
|
||||
|
||||
def test_arize_construct_dynamic_headers(self):
|
||||
"""Test dynamic OTEL headers construction for team/key logging."""
|
||||
|
|
@ -180,4 +184,4 @@ class TestArizeIntegrationWithProxy:
|
|||
|
||||
|
||||
if __name__ == "__main__":
|
||||
pytest.main([__file__, "-v"])
|
||||
pytest.main([__file__, "-v"])
|
||||
|
|
|
|||
|
|
@ -1,18 +1,19 @@
|
|||
import os
|
||||
import sys
|
||||
from unittest.mock import MagicMock, patch
|
||||
|
||||
import pytest
|
||||
|
||||
sys.path.insert(0, os.path.abspath("../../..")) # Adds the parent directory to the system path
|
||||
|
||||
from litellm.integrations.gitlab.gitlab_client import GitLabClient
|
||||
from litellm.integrations.gitlab.gitlab_prompt_manager import (
|
||||
GitLabPromptCache,
|
||||
GitLabPromptManager,
|
||||
GitLabPromptTemplate,
|
||||
GitLabTemplateManager,
|
||||
GitLabPromptCache,
|
||||
encode_prompt_id,
|
||||
decode_prompt_id,
|
||||
encode_prompt_id,
|
||||
)
|
||||
|
||||
# -----------------------
|
||||
|
|
@ -817,22 +818,3 @@ def test_cache_get_by_file_returns_exact_entry(mock_pm_cls, fake_managers):
|
|||
assert beta and beta["id"] == "nested/beta"
|
||||
|
||||
|
||||
@patch("litellm.integrations.gitlab.gitlab_prompt_manager.GitLabPromptManager")
|
||||
def test_encode_decode_helpers_roundtrip_in_cache_context(mock_pm_cls, fake_managers):
|
||||
tm, wrapper = fake_managers
|
||||
tm._discoverable_ids = ["dir1/dir2/item"]
|
||||
mock_pm_cls.return_value = wrapper
|
||||
|
||||
cache = GitLabPromptCache({"project": "g/s/r", "access_token": "tkn"})
|
||||
cache.load_all()
|
||||
|
||||
encoded = encode_prompt_id("dir1/dir2/item")
|
||||
assert encoded in cache.list_ids()
|
||||
|
||||
# decode → encode → lookup should still work
|
||||
decoded = decode_prompt_id(encoded)
|
||||
assert decoded == "dir1/dir2/item"
|
||||
|
||||
got = cache.get_by_id(decoded)
|
||||
assert got is not None
|
||||
assert got["id"] == "dir1/dir2/item"
|
||||
|
|
@ -9,10 +9,10 @@ from litellm.integrations.opentelemetry import OpenTelemetryConfig
|
|||
# Try to import OpenTelemetry packages, skip tests if not available
|
||||
try:
|
||||
from opentelemetry.sdk.trace import TracerProvider
|
||||
from opentelemetry.sdk.trace.export import SimpleSpanProcessor
|
||||
from opentelemetry.sdk.trace.export.in_memory_span_exporter import (
|
||||
InMemorySpanExporter,
|
||||
)
|
||||
from opentelemetry.sdk.trace.export import SimpleSpanProcessor
|
||||
|
||||
OPENTELEMETRY_AVAILABLE = True
|
||||
except ImportError:
|
||||
|
|
@ -150,53 +150,6 @@ class TestLevoConfig(unittest.TestCase):
|
|||
|
||||
class TestLevoIntegration(unittest.TestCase):
|
||||
"""Integration tests for LevoLogger."""
|
||||
|
||||
@patch.dict(
|
||||
"os.environ",
|
||||
{
|
||||
"LEVOAI_API_KEY": "test-api-key",
|
||||
"LEVOAI_ORG_ID": "test-org-id",
|
||||
"LEVOAI_WORKSPACE_ID": "test-workspace-id",
|
||||
"LEVOAI_COLLECTOR_URL": "https://collector.levo.ai",
|
||||
},
|
||||
)
|
||||
@pytest.mark.skipif(
|
||||
not OPENTELEMETRY_AVAILABLE, reason="OpenTelemetry packages not installed"
|
||||
)
|
||||
@patch(
|
||||
"litellm.integrations.opentelemetry.OpenTelemetry._init_otel_logger_on_litellm_proxy"
|
||||
)
|
||||
def test_levo_logger_instantiation(self, mock_init_proxy):
|
||||
"""Test that LevoLogger can be instantiated with proper config."""
|
||||
# Mock the proxy initialization to avoid importing proxy code
|
||||
mock_init_proxy.return_value = None
|
||||
|
||||
config = LevoLogger.get_levo_config()
|
||||
otel_config = OpenTelemetryConfig(
|
||||
exporter=config.protocol,
|
||||
endpoint=config.endpoint,
|
||||
headers=config.otlp_auth_headers,
|
||||
)
|
||||
|
||||
# Create a tracer provider with in-memory exporter to avoid requiring OTLP packages
|
||||
tracer_provider = TracerProvider()
|
||||
tracer_provider.add_span_processor(SimpleSpanProcessor(InMemorySpanExporter()))
|
||||
|
||||
# Create LevoLogger instance with mocked tracer provider
|
||||
levo_logger = LevoLogger(
|
||||
config=otel_config, callback_name="levo", tracer_provider=tracer_provider
|
||||
)
|
||||
|
||||
# Verify it's an instance of OpenTelemetry
|
||||
self.assertIsInstance(levo_logger, LevoLogger)
|
||||
# Check it extends OpenTelemetry by checking base classes
|
||||
from litellm.integrations.opentelemetry import OpenTelemetry
|
||||
|
||||
self.assertIsInstance(levo_logger, OpenTelemetry)
|
||||
|
||||
# Verify callback_name is set
|
||||
self.assertEqual(levo_logger.callback_name, "levo")
|
||||
|
||||
@patch.dict(
|
||||
"os.environ",
|
||||
{
|
||||
|
|
|
|||
|
|
@ -258,6 +258,22 @@ class TestOpenTelemetry(unittest.TestCase):
|
|||
MODEL = "arn:aws:bedrock:us-west-2:1234567890123:inference-profile/us.anthropic.claude-3-7-sonnet-20250219-v1:0"
|
||||
HERE = os.path.dirname(__file__)
|
||||
|
||||
@patch.dict(os.environ, {}, clear=True)
|
||||
def test_open_telemetry_config_manual_defaults(self):
|
||||
"""Manual OpenTelemetryConfig creation should populate default identifiers."""
|
||||
config = OpenTelemetryConfig(exporter="console", endpoint="http://collector")
|
||||
self.assertEqual(config.service_name, "litellm")
|
||||
self.assertEqual(config.deployment_environment, "production")
|
||||
self.assertEqual(config.model_id, "litellm")
|
||||
|
||||
@patch.dict(os.environ, {}, clear=True)
|
||||
def test_open_telemetry_config_custom_service_name(self):
|
||||
"""Model ID should inherit provided service name when not explicitly set."""
|
||||
config = OpenTelemetryConfig(service_name="custom-service", exporter="console")
|
||||
self.assertEqual(config.service_name, "custom-service")
|
||||
self.assertEqual(config.deployment_environment, "production")
|
||||
self.assertEqual(config.model_id, "custom-service")
|
||||
|
||||
def wait_for_spans(self, exporter: InMemorySpanExporter, prefix: str):
|
||||
"""Poll until we see at least one span with an attribute key starting with `prefix`."""
|
||||
deadline = time.time() + self.POLL_TIMEOUT
|
||||
|
|
@ -504,8 +520,6 @@ class TestOpenTelemetry(unittest.TestCase):
|
|||
self, mock_detector_cls, mock_resource_create
|
||||
):
|
||||
"""Test _get_litellm_resource with default values when no environment variables are set."""
|
||||
from litellm.integrations.opentelemetry import _get_litellm_resource
|
||||
|
||||
# Mock the Resource.create method
|
||||
mock_base_resource = MagicMock()
|
||||
mock_resource_create.return_value = mock_base_resource
|
||||
|
|
@ -520,8 +534,8 @@ class TestOpenTelemetry(unittest.TestCase):
|
|||
mock_merged_resource = MagicMock()
|
||||
mock_base_resource.merge.return_value = mock_merged_resource
|
||||
|
||||
# Call the function
|
||||
result = _get_litellm_resource()
|
||||
config = OpenTelemetryConfig()
|
||||
result = OpenTelemetry._get_litellm_resource(config)
|
||||
|
||||
# Verify Resource.create was called with correct default attributes
|
||||
expected_attributes = {
|
||||
|
|
@ -549,8 +563,6 @@ class TestOpenTelemetry(unittest.TestCase):
|
|||
self, mock_detector_cls, mock_resource_create
|
||||
):
|
||||
"""Test _get_litellm_resource with LiteLLM-specific environment variables."""
|
||||
from litellm.integrations.opentelemetry import _get_litellm_resource
|
||||
|
||||
# Mock the Resource.create method
|
||||
mock_base_resource = MagicMock()
|
||||
mock_resource_create.return_value = mock_base_resource
|
||||
|
|
@ -565,8 +577,8 @@ class TestOpenTelemetry(unittest.TestCase):
|
|||
mock_merged_resource = MagicMock()
|
||||
mock_base_resource.merge.return_value = mock_merged_resource
|
||||
|
||||
# Call the function
|
||||
result = _get_litellm_resource()
|
||||
config = OpenTelemetryConfig.from_env()
|
||||
result = OpenTelemetry._get_litellm_resource(config)
|
||||
|
||||
# Verify Resource.create was called with environment variable values
|
||||
expected_attributes = {
|
||||
|
|
@ -593,8 +605,6 @@ class TestOpenTelemetry(unittest.TestCase):
|
|||
self, mock_detector_cls, mock_resource_create
|
||||
):
|
||||
"""Test _get_litellm_resource with OTEL_RESOURCE_ATTRIBUTES environment variable."""
|
||||
from litellm.integrations.opentelemetry import _get_litellm_resource
|
||||
|
||||
# Mock the Resource.create method to simulate the actual behavior
|
||||
# In reality, Resource.create() would parse OTEL_RESOURCE_ATTRIBUTES and merge it
|
||||
mock_base_resource = MagicMock()
|
||||
|
|
@ -610,8 +620,8 @@ class TestOpenTelemetry(unittest.TestCase):
|
|||
mock_merged_resource = MagicMock()
|
||||
mock_base_resource.merge.return_value = mock_merged_resource
|
||||
|
||||
# Call the function
|
||||
result = _get_litellm_resource()
|
||||
config = OpenTelemetryConfig.from_env()
|
||||
result = OpenTelemetry._get_litellm_resource(config)
|
||||
|
||||
# Verify Resource.create was called with the base attributes
|
||||
# The actual OTEL_RESOURCE_ATTRIBUTES parsing is handled by OpenTelemetry SDK
|
||||
|
|
@ -628,10 +638,8 @@ class TestOpenTelemetry(unittest.TestCase):
|
|||
@patch.dict(os.environ, {}, clear=True)
|
||||
def test_get_litellm_resource_integration_with_real_resource(self):
|
||||
"""Integration test to verify _get_litellm_resource works with actual OpenTelemetry Resource."""
|
||||
from litellm.integrations.opentelemetry import _get_litellm_resource
|
||||
|
||||
# This test uses the real OpenTelemetry Resource.create() method
|
||||
result = _get_litellm_resource()
|
||||
config = OpenTelemetryConfig()
|
||||
result = OpenTelemetry._get_litellm_resource(config)
|
||||
|
||||
# Verify the result is a Resource instance
|
||||
from opentelemetry.sdk.resources import Resource
|
||||
|
|
@ -653,10 +661,8 @@ class TestOpenTelemetry(unittest.TestCase):
|
|||
)
|
||||
def test_get_litellm_resource_real_otel_resource_attributes(self):
|
||||
"""Integration test to verify OTEL_RESOURCE_ATTRIBUTES is properly handled."""
|
||||
from litellm.integrations.opentelemetry import _get_litellm_resource
|
||||
|
||||
# This test uses the real OpenTelemetry Resource.create() method
|
||||
result = _get_litellm_resource()
|
||||
config = OpenTelemetryConfig.from_env()
|
||||
result = OpenTelemetry._get_litellm_resource(config)
|
||||
|
||||
print("RESULT", result)
|
||||
|
||||
|
|
@ -683,10 +689,8 @@ class TestOpenTelemetry(unittest.TestCase):
|
|||
)
|
||||
def test_get_litellm_resource_precedence(self):
|
||||
"""Test that OTEL_SERVICE_NAME takes precedence over OTEL_RESOURCE_ATTRIBUTES according to OpenTelemetry spec."""
|
||||
from litellm.integrations.opentelemetry import _get_litellm_resource
|
||||
|
||||
# This test verifies the OpenTelemetry standard behavior
|
||||
result = _get_litellm_resource()
|
||||
config = OpenTelemetryConfig.from_env()
|
||||
result = OpenTelemetry._get_litellm_resource(config)
|
||||
|
||||
# Verify the result is a Resource instance
|
||||
from opentelemetry.sdk.resources import Resource
|
||||
|
|
|
|||
|
|
@ -570,6 +570,7 @@ async def test_ensure_initialize_azure_sdk_client_always_used(call_type):
|
|||
or call_type == CallTypes.acreate_container
|
||||
or call_type == CallTypes.adelete_container
|
||||
or call_type == CallTypes.alist_container_files
|
||||
or call_type == CallTypes.aupload_container_file
|
||||
):
|
||||
# Skip container call types as they're not supported for Azure (only OpenAI)
|
||||
pytest.skip(f"Skipping {call_type.value} because Azure doesn't support container operations")
|
||||
|
|
|
|||
|
|
@ -1279,7 +1279,7 @@ async def test_update_team_team_member_budget_not_passed_to_db():
|
|||
|
||||
# Mock budget upsert to return updated_kv without team_member_budget
|
||||
def mock_upsert_side_effect(
|
||||
team_table, user_api_key_dict, updated_kv, team_member_budget=None, team_member_rpm_limit=None, team_member_tpm_limit=None
|
||||
team_table, user_api_key_dict, updated_kv, team_member_budget=None, team_member_rpm_limit=None, team_member_tpm_limit=None, team_member_budget_duration=None
|
||||
):
|
||||
# Remove team_member_budget from updated_kv as the real function does
|
||||
result_kv = updated_kv.copy()
|
||||
|
|
@ -1376,6 +1376,370 @@ async def test_update_team_team_member_budget_not_passed_to_db():
|
|||
)
|
||||
|
||||
|
||||
def test_clean_team_member_fields():
|
||||
"""
|
||||
Test that _clean_team_member_fields removes all team member fields from a dictionary.
|
||||
"""
|
||||
from litellm.proxy.management_endpoints.team_endpoints import (
|
||||
TeamMemberBudgetHandler,
|
||||
)
|
||||
|
||||
data_dict = {
|
||||
"team_id": "test_team",
|
||||
"team_alias": "Test Team",
|
||||
"team_member_budget": 100.0,
|
||||
"team_member_budget_duration": "30d",
|
||||
"team_member_rpm_limit": 50,
|
||||
"team_member_tpm_limit": 1000,
|
||||
"other_field": "should_remain",
|
||||
}
|
||||
|
||||
TeamMemberBudgetHandler._clean_team_member_fields(data_dict)
|
||||
|
||||
assert "team_member_budget" not in data_dict
|
||||
assert "team_member_budget_duration" not in data_dict
|
||||
assert "team_member_rpm_limit" not in data_dict
|
||||
assert "team_member_tpm_limit" not in data_dict
|
||||
assert data_dict["team_id"] == "test_team"
|
||||
assert data_dict["team_alias"] == "Test Team"
|
||||
assert data_dict["other_field"] == "should_remain"
|
||||
|
||||
|
||||
def test_clean_team_member_fields_with_missing_fields():
|
||||
"""
|
||||
Test that _clean_team_member_fields handles dictionaries without team member fields gracefully.
|
||||
"""
|
||||
from litellm.proxy.management_endpoints.team_endpoints import (
|
||||
TeamMemberBudgetHandler,
|
||||
)
|
||||
|
||||
data_dict = {
|
||||
"team_id": "test_team",
|
||||
"team_alias": "Test Team",
|
||||
}
|
||||
|
||||
TeamMemberBudgetHandler._clean_team_member_fields(data_dict)
|
||||
|
||||
assert data_dict["team_id"] == "test_team"
|
||||
assert data_dict["team_alias"] == "Test Team"
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_create_team_member_budget_table():
|
||||
"""
|
||||
Test that create_team_member_budget_table creates a budget and adds it to metadata.
|
||||
"""
|
||||
from unittest.mock import AsyncMock, MagicMock, patch
|
||||
|
||||
from litellm.proxy._types import LitellmUserRoles, NewTeamRequest, UserAPIKeyAuth
|
||||
from litellm.proxy.management_endpoints.team_endpoints import (
|
||||
TeamMemberBudgetHandler,
|
||||
)
|
||||
|
||||
mock_user_api_key_dict = UserAPIKeyAuth(
|
||||
user_role=LitellmUserRoles.PROXY_ADMIN, user_id="test_user_id"
|
||||
)
|
||||
|
||||
data = NewTeamRequest(
|
||||
team_id="test_team_id",
|
||||
team_alias="Test Team",
|
||||
budget_duration="1mo",
|
||||
)
|
||||
new_team_data_json = {
|
||||
"team_id": "test_team_id",
|
||||
"team_alias": "Test Team",
|
||||
"team_member_budget": 100.0,
|
||||
"team_member_budget_duration": "30d",
|
||||
"team_member_rpm_limit": 50,
|
||||
"team_member_tpm_limit": 1000,
|
||||
}
|
||||
|
||||
mock_budget_response = MagicMock()
|
||||
mock_budget_response.budget_id = "budget_123"
|
||||
|
||||
with patch(
|
||||
"litellm.proxy.management_endpoints.budget_management_endpoints.new_budget",
|
||||
new_callable=AsyncMock
|
||||
) as mock_new_budget:
|
||||
mock_new_budget.return_value = mock_budget_response
|
||||
|
||||
result = await TeamMemberBudgetHandler.create_team_member_budget_table(
|
||||
data=data,
|
||||
new_team_data_json=new_team_data_json,
|
||||
user_api_key_dict=mock_user_api_key_dict,
|
||||
team_member_budget=100.0,
|
||||
team_member_rpm_limit=50,
|
||||
team_member_tpm_limit=1000,
|
||||
team_member_budget_duration="30d",
|
||||
)
|
||||
|
||||
assert mock_new_budget.called
|
||||
call_args = mock_new_budget.call_args
|
||||
budget_request = call_args[1]["budget_obj"]
|
||||
|
||||
assert budget_request.max_budget == 100.0
|
||||
assert budget_request.rpm_limit == 50
|
||||
assert budget_request.tpm_limit == 1000
|
||||
assert budget_request.budget_duration == "30d"
|
||||
assert budget_request.budget_id is not None
|
||||
assert "team-" in budget_request.budget_id
|
||||
|
||||
assert "team_member_budget_id" in result["metadata"]
|
||||
assert result["metadata"]["team_member_budget_id"] == "budget_123"
|
||||
|
||||
assert "team_member_budget" not in result
|
||||
assert "team_member_budget_duration" not in result
|
||||
assert "team_member_rpm_limit" not in result
|
||||
assert "team_member_tpm_limit" not in result
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_create_team_member_budget_table_without_team_alias():
|
||||
"""
|
||||
Test that create_team_member_budget_table generates budget_id correctly when team_alias is None.
|
||||
"""
|
||||
from unittest.mock import AsyncMock, MagicMock, patch
|
||||
|
||||
from litellm.proxy._types import LitellmUserRoles, NewTeamRequest, UserAPIKeyAuth
|
||||
from litellm.proxy.management_endpoints.team_endpoints import (
|
||||
TeamMemberBudgetHandler,
|
||||
)
|
||||
|
||||
mock_user_api_key_dict = UserAPIKeyAuth(
|
||||
user_role=LitellmUserRoles.PROXY_ADMIN, user_id="test_user_id"
|
||||
)
|
||||
|
||||
data = NewTeamRequest(team_id="test_team_id")
|
||||
new_team_data_json = {
|
||||
"team_id": "test_team_id",
|
||||
"team_member_budget": 100.0,
|
||||
}
|
||||
|
||||
mock_budget_response = MagicMock()
|
||||
mock_budget_response.budget_id = "budget_123"
|
||||
|
||||
with patch(
|
||||
"litellm.proxy.management_endpoints.budget_management_endpoints.new_budget",
|
||||
new_callable=AsyncMock
|
||||
) as mock_new_budget:
|
||||
mock_new_budget.return_value = mock_budget_response
|
||||
|
||||
result = await TeamMemberBudgetHandler.create_team_member_budget_table(
|
||||
data=data,
|
||||
new_team_data_json=new_team_data_json,
|
||||
user_api_key_dict=mock_user_api_key_dict,
|
||||
team_member_budget=100.0,
|
||||
)
|
||||
|
||||
assert mock_new_budget.called
|
||||
call_args = mock_new_budget.call_args
|
||||
budget_request = call_args[1]["budget_obj"]
|
||||
|
||||
assert budget_request.budget_id is not None
|
||||
assert budget_request.budget_id.startswith("team-budget-")
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_upsert_team_member_budget_table_existing_budget():
|
||||
"""
|
||||
Test that upsert_team_member_budget_table updates an existing budget when team_member_budget_id exists.
|
||||
"""
|
||||
from unittest.mock import AsyncMock, MagicMock, patch
|
||||
|
||||
from litellm.proxy._types import LitellmUserRoles, LiteLLM_TeamTable, UserAPIKeyAuth
|
||||
from litellm.proxy.management_endpoints.team_endpoints import (
|
||||
TeamMemberBudgetHandler,
|
||||
)
|
||||
|
||||
mock_user_api_key_dict = UserAPIKeyAuth(
|
||||
user_role=LitellmUserRoles.PROXY_ADMIN, user_id="test_user_id"
|
||||
)
|
||||
|
||||
team_table = MagicMock(spec=LiteLLM_TeamTable)
|
||||
team_table.metadata = {"team_member_budget_id": "existing_budget_123"}
|
||||
|
||||
updated_kv = {
|
||||
"team_id": "test_team_id",
|
||||
"team_member_budget": 200.0,
|
||||
"team_member_budget_duration": "60d",
|
||||
"team_member_rpm_limit": 100,
|
||||
}
|
||||
|
||||
mock_budget_response = MagicMock()
|
||||
mock_budget_response.budget_id = "existing_budget_123"
|
||||
|
||||
with patch(
|
||||
"litellm.proxy.management_endpoints.budget_management_endpoints.update_budget",
|
||||
new_callable=AsyncMock
|
||||
) as mock_update_budget:
|
||||
mock_update_budget.return_value = mock_budget_response
|
||||
|
||||
result = await TeamMemberBudgetHandler.upsert_team_member_budget_table(
|
||||
team_table=team_table,
|
||||
user_api_key_dict=mock_user_api_key_dict,
|
||||
updated_kv=updated_kv,
|
||||
team_member_budget=200.0,
|
||||
team_member_budget_duration="60d",
|
||||
team_member_rpm_limit=100,
|
||||
)
|
||||
|
||||
assert mock_update_budget.called
|
||||
call_args = mock_update_budget.call_args
|
||||
budget_request = call_args[1]["budget_obj"]
|
||||
|
||||
assert budget_request.budget_id == "existing_budget_123"
|
||||
assert budget_request.max_budget == 200.0
|
||||
assert budget_request.budget_duration == "60d"
|
||||
assert budget_request.rpm_limit == 100
|
||||
|
||||
assert "team_member_budget_id" in result["metadata"]
|
||||
assert result["metadata"]["team_member_budget_id"] == "existing_budget_123"
|
||||
|
||||
assert "team_member_budget" not in result
|
||||
assert "team_member_budget_duration" not in result
|
||||
assert "team_member_rpm_limit" not in result
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_upsert_team_member_budget_table_no_existing_budget():
|
||||
"""
|
||||
Test that upsert_team_member_budget_table creates a new budget when team_member_budget_id does not exist.
|
||||
"""
|
||||
from unittest.mock import AsyncMock, MagicMock, patch
|
||||
|
||||
from litellm.proxy._types import LitellmUserRoles, LiteLLM_TeamTable, UserAPIKeyAuth
|
||||
from litellm.proxy.management_endpoints.team_endpoints import (
|
||||
TeamMemberBudgetHandler,
|
||||
)
|
||||
|
||||
mock_user_api_key_dict = UserAPIKeyAuth(
|
||||
user_role=LitellmUserRoles.PROXY_ADMIN, user_id="test_user_id"
|
||||
)
|
||||
|
||||
team_table = MagicMock(spec=LiteLLM_TeamTable)
|
||||
team_table.metadata = {}
|
||||
team_table.team_alias = "Test Team"
|
||||
team_table.budget_duration = None
|
||||
|
||||
updated_kv = {
|
||||
"team_id": "test_team_id",
|
||||
"team_member_budget": 150.0,
|
||||
"team_member_budget_duration": "45d",
|
||||
}
|
||||
|
||||
mock_budget_response = MagicMock()
|
||||
mock_budget_response.budget_id = "new_budget_456"
|
||||
|
||||
with patch(
|
||||
"litellm.proxy.management_endpoints.budget_management_endpoints.new_budget",
|
||||
new_callable=AsyncMock
|
||||
) as mock_new_budget:
|
||||
mock_new_budget.return_value = mock_budget_response
|
||||
|
||||
result = await TeamMemberBudgetHandler.upsert_team_member_budget_table(
|
||||
team_table=team_table,
|
||||
user_api_key_dict=mock_user_api_key_dict,
|
||||
updated_kv=updated_kv,
|
||||
team_member_budget=150.0,
|
||||
team_member_budget_duration="45d",
|
||||
)
|
||||
|
||||
assert mock_new_budget.called
|
||||
assert "team_member_budget_id" in result["metadata"]
|
||||
assert result["metadata"]["team_member_budget_id"] == "new_budget_456"
|
||||
|
||||
assert "team_member_budget" not in result
|
||||
assert "team_member_budget_duration" not in result
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_update_team_with_team_member_budget_duration():
|
||||
"""
|
||||
Test that team/update endpoint properly handles team_member_budget_duration.
|
||||
"""
|
||||
from unittest.mock import AsyncMock, MagicMock, Mock, patch
|
||||
|
||||
from fastapi import Request
|
||||
|
||||
from litellm.proxy._types import LitellmUserRoles, UpdateTeamRequest, UserAPIKeyAuth
|
||||
from litellm.proxy.management_endpoints.team_endpoints import update_team
|
||||
|
||||
mock_request = Mock(spec=Request)
|
||||
mock_user_api_key_dict = UserAPIKeyAuth(
|
||||
user_role=LitellmUserRoles.PROXY_ADMIN, user_id="test_user_id"
|
||||
)
|
||||
|
||||
with patch("litellm.proxy.proxy_server.prisma_client") as mock_prisma_client, patch(
|
||||
"litellm.proxy.proxy_server.llm_router"
|
||||
) as mock_llm_router, patch(
|
||||
"litellm.proxy.proxy_server.user_api_key_cache"
|
||||
) as mock_cache, patch(
|
||||
"litellm.proxy.proxy_server.proxy_logging_obj"
|
||||
) as mock_logging, patch(
|
||||
"litellm.proxy.proxy_server.litellm_proxy_admin_name", "admin"
|
||||
), patch(
|
||||
"litellm.proxy.auth.auth_checks._cache_team_object"
|
||||
) as mock_cache_team, patch(
|
||||
"litellm.proxy.management_endpoints.team_endpoints.TeamMemberBudgetHandler.upsert_team_member_budget_table"
|
||||
) as mock_upsert_budget:
|
||||
|
||||
mock_existing_team = MagicMock()
|
||||
mock_existing_team.model_dump.return_value = {
|
||||
"team_id": "test_team_id",
|
||||
"team_alias": "test_team",
|
||||
"metadata": {"team_member_budget_id": "budget_123"},
|
||||
}
|
||||
mock_existing_team.metadata = {"team_member_budget_id": "budget_123"}
|
||||
mock_prisma_client.db.litellm_teamtable.find_unique = AsyncMock(
|
||||
return_value=mock_existing_team
|
||||
)
|
||||
|
||||
mock_updated_team = MagicMock()
|
||||
mock_updated_team.team_id = "test_team_id"
|
||||
mock_updated_team.model_dump.return_value = {"team_id": "test_team_id"}
|
||||
mock_prisma_client.db.litellm_teamtable.update = AsyncMock(
|
||||
return_value=mock_updated_team
|
||||
)
|
||||
mock_prisma_client.jsonify_team_object = MagicMock(
|
||||
side_effect=lambda db_data: db_data
|
||||
)
|
||||
|
||||
def mock_upsert_side_effect(
|
||||
team_table, user_api_key_dict, updated_kv, team_member_budget=None, team_member_rpm_limit=None, team_member_tpm_limit=None, team_member_budget_duration=None
|
||||
):
|
||||
result_kv = updated_kv.copy()
|
||||
result_kv.pop("team_member_budget", None)
|
||||
result_kv.pop("team_member_budget_duration", None)
|
||||
return result_kv
|
||||
|
||||
mock_upsert_budget.side_effect = mock_upsert_side_effect
|
||||
|
||||
update_request = UpdateTeamRequest(
|
||||
team_id="test_team_id",
|
||||
team_alias="updated_alias",
|
||||
team_member_budget=100.0,
|
||||
team_member_budget_duration="30d",
|
||||
)
|
||||
|
||||
result = await update_team(
|
||||
data=update_request,
|
||||
http_request=mock_request,
|
||||
user_api_key_dict=mock_user_api_key_dict,
|
||||
)
|
||||
|
||||
assert mock_upsert_budget.called
|
||||
call_args = mock_upsert_budget.call_args
|
||||
assert call_args[1]["team_member_budget"] == 100.0
|
||||
assert call_args[1]["team_member_budget_duration"] == "30d"
|
||||
|
||||
assert mock_prisma_client.db.litellm_teamtable.update.called
|
||||
update_call_args = mock_prisma_client.db.litellm_teamtable.update.call_args
|
||||
update_data = update_call_args[1]["data"]
|
||||
|
||||
assert "team_member_budget" not in update_data
|
||||
assert "team_member_budget_duration" not in update_data
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_bulk_team_member_add_success():
|
||||
"""
|
||||
|
|
|
|||
87
tests/test_litellm/test_eager_tiktoken_load.py
Normal file
87
tests/test_litellm/test_eager_tiktoken_load.py
Normal file
|
|
@ -0,0 +1,87 @@
|
|||
"""
|
||||
Test for LITELLM_DISABLE_LAZY_LOADING environment variable.
|
||||
|
||||
This test verifies that when LITELLM_DISABLE_LAZY_LOADING is set,
|
||||
encoding is loaded at import time (pre-#18070 behavior) instead of lazy loading.
|
||||
|
||||
This addresses issue #18659: VCR cassette creation broken by lazy loading.
|
||||
For now, this only affects encoding as it was the only reported issue.
|
||||
"""
|
||||
import os
|
||||
import sys
|
||||
import pytest
|
||||
|
||||
|
||||
def test_eager_loading_enabled():
|
||||
"""Test that encoding is loaded at import time when env var is set"""
|
||||
# Set environment variable
|
||||
os.environ["LITELLM_DISABLE_LAZY_LOADING"] = "1"
|
||||
|
||||
# Clear any cached modules to ensure fresh import
|
||||
modules_to_clear = [k for k in sys.modules.keys() if k.startswith("litellm")]
|
||||
for module in modules_to_clear:
|
||||
del sys.modules[module]
|
||||
|
||||
# Import litellm - encoding should be loaded immediately
|
||||
import litellm
|
||||
|
||||
# Check that encoding is available (not lazy loaded)
|
||||
assert hasattr(litellm, "encoding"), "Encoding should be available when eager loading is enabled"
|
||||
|
||||
# Verify it's actually the encoding object
|
||||
encoding = litellm.encoding
|
||||
assert encoding is not None, "Encoding should not be None"
|
||||
|
||||
# Test that it works
|
||||
tokens = encoding.encode("Hello, world!")
|
||||
assert len(tokens) > 0, "Encoding should work"
|
||||
|
||||
|
||||
def test_eager_loading_env_var_values():
|
||||
"""Test that various env var values enable eager loading"""
|
||||
values = ["1", "true", "True", "TRUE", "yes", "Yes", "YES", "on", "On", "ON"]
|
||||
|
||||
for value in values:
|
||||
os.environ["LITELLM_DISABLE_LAZY_LOADING"] = value
|
||||
|
||||
# Clear modules
|
||||
modules_to_clear = [k for k in sys.modules.keys() if k.startswith("litellm")]
|
||||
for module in modules_to_clear:
|
||||
del sys.modules[module]
|
||||
|
||||
import litellm
|
||||
assert hasattr(litellm, "encoding"), f"Encoding should be available for value: {value}"
|
||||
encoding = litellm.encoding
|
||||
tokens = encoding.encode("test")
|
||||
assert len(tokens) > 0
|
||||
|
||||
|
||||
def test_lazy_loading_default():
|
||||
"""Test that encoding is lazy loaded by default (when env var is not set)"""
|
||||
# Remove environment variable if set
|
||||
if "LITELLM_DISABLE_LAZY_LOADING" in os.environ:
|
||||
del os.environ["LITELLM_DISABLE_LAZY_LOADING"]
|
||||
|
||||
# Clear any cached modules
|
||||
modules_to_clear = [k for k in sys.modules.keys() if k.startswith("litellm")]
|
||||
for module in modules_to_clear:
|
||||
del sys.modules[module]
|
||||
|
||||
# Import litellm - encoding should NOT be loaded yet
|
||||
import litellm
|
||||
|
||||
# Encoding should be accessible via __getattr__ (lazy loading)
|
||||
encoding = litellm.encoding # This triggers lazy loading
|
||||
|
||||
# Verify it works
|
||||
tokens = encoding.encode("Hello, world!")
|
||||
assert len(tokens) > 0, "Encoding should work"
|
||||
|
||||
|
||||
@pytest.fixture(autouse=True)
|
||||
def cleanup_env():
|
||||
"""Clean up environment variable after each test"""
|
||||
yield
|
||||
if "LITELLM_DISABLE_LAZY_LOADING" in os.environ:
|
||||
del os.environ["LITELLM_DISABLE_LAZY_LOADING"]
|
||||
|
||||
|
|
@ -136,10 +136,9 @@ class TestEncryptResponseId:
|
|||
)
|
||||
|
||||
with patch(
|
||||
"litellm.proxy.hooks.responses_id_security.encrypt_value_helper"
|
||||
) as mock_encrypt:
|
||||
mock_encrypt.return_value = "encrypted_value_456"
|
||||
|
||||
"litellm.proxy.common_utils.encrypt_decrypt_utils._get_salt_key",
|
||||
return_value="test-salt-key"
|
||||
):
|
||||
with patch.object(
|
||||
responses_id_security, "_get_signing_key", return_value="test-key"
|
||||
):
|
||||
|
|
@ -148,6 +147,8 @@ class TestEncryptResponseId:
|
|||
)
|
||||
|
||||
assert result.id.startswith("resp_")
|
||||
# The encrypted ID should be different from the original
|
||||
assert result.id != "resp_456"
|
||||
|
||||
|
||||
class TestCheckUserAccessToResponseId:
|
||||
|
|
|
|||
|
|
@ -5,7 +5,7 @@ test.describe("Add Model", () => {
|
|||
test.use({ storageState: ADMIN_STORAGE_PATH });
|
||||
|
||||
test("Able to see all models for a specific provider in the model dropdown", async ({ page }) => {
|
||||
await page.goto("http://localhost:4000/ui");
|
||||
await page.goto("/ui");
|
||||
|
||||
await page.getByText("Models + Endpoints").click();
|
||||
await page.getByRole("tab", { name: "Add Model" }).click();
|
||||
|
|
|
|||
|
|
@ -24,7 +24,7 @@ for (const { role, storage } of roles) {
|
|||
test.use({ storageState: storage });
|
||||
|
||||
test("can see and navigate all sidebar buttons", async ({ page }) => {
|
||||
await page.goto("http://localhost:4000/ui");
|
||||
await page.goto("/ui");
|
||||
for (const button of sidebarButtons[role as keyof typeof sidebarButtons]) {
|
||||
const tab = page.getByRole("menuitem", { name: button });
|
||||
await expect(tab).toBeVisible();
|
||||
|
|
|
|||
|
|
@ -0,0 +1,14 @@
|
|||
import { test, expect } from "@playwright/test";
|
||||
import { ADMIN_STORAGE_PATH } from "../../constants";
|
||||
|
||||
test.describe("Add Model", () => {
|
||||
test.use({ storageState: ADMIN_STORAGE_PATH });
|
||||
|
||||
test("admin settings test", async ({ page }) => {
|
||||
await page.goto("/ui");
|
||||
await page.getByRole("menuitem", { name: /Settings/ }).click();
|
||||
await page.getByRole("menuitem", { name: /Admin Settings/ }).click();
|
||||
await page.getByRole("tab", { name: "UI Settings" }).click();
|
||||
await expect(page.getByText("Configuration for UI-specific")).toBeVisible();
|
||||
});
|
||||
});
|
||||
|
|
@ -1,9 +1,10 @@
|
|||
import { test, expect, Page } from "@playwright/test";
|
||||
import { ADMIN_STORAGE_PATH } from "../../constants";
|
||||
test.describe("Internal Users Search", () => {
|
||||
test.use({ storageState: "admin.storageState.json" });
|
||||
test.use({ storageState: ADMIN_STORAGE_PATH });
|
||||
|
||||
async function goToInternalUsers(page: Page) {
|
||||
await page.goto("http://localhost:4000/ui");
|
||||
await page.goto("/ui");
|
||||
|
||||
const tab = page.getByRole("menuitem", { name: "Internal User" });
|
||||
await expect(tab).toBeVisible();
|
||||
|
|
|
|||
|
|
@ -1,10 +1,11 @@
|
|||
import { test, expect, Page } from "@playwright/test";
|
||||
import { ADMIN_STORAGE_PATH } from "../../constants";
|
||||
|
||||
test.describe("Internal Users Page", () => {
|
||||
test.use({ storageState: "admin.storageState.json" });
|
||||
test.use({ storageState: ADMIN_STORAGE_PATH });
|
||||
|
||||
async function goToInternalUsers(page: Page) {
|
||||
await page.goto("http://localhost:4000/ui");
|
||||
await page.goto("/ui");
|
||||
|
||||
const internalUserTab = page.getByRole("menuitem", { name: "Internal User" });
|
||||
await expect(internalUserTab).toBeVisible();
|
||||
|
|
@ -43,6 +44,7 @@ test.describe("Internal Users Page", () => {
|
|||
await expect(prevButton).toBeDisabled();
|
||||
}
|
||||
|
||||
await page.waitForTimeout(1000);
|
||||
// Check if there are more pages
|
||||
const hasMorePages = infoText.includes("of") && !infoText.endsWith("25 of 25");
|
||||
if (hasMorePages) {
|
||||
|
|
|
|||
|
|
@ -279,12 +279,13 @@ const ModelsAndEndpointsView: React.FC<ModelDashboardProps> = ({ premiumUser, te
|
|||
{/* Missing Provider Banner */}
|
||||
<div className="mb-4 px-4 py-3 bg-blue-50 rounded-lg border border-blue-100 flex items-center gap-4">
|
||||
<div className="flex-shrink-0 w-10 h-10 bg-white rounded-full flex items-center justify-center border border-blue-200">
|
||||
<PlusCircleOutlined style={{ fontSize: '18px', color: '#6366f1' }} />
|
||||
<PlusCircleOutlined style={{ fontSize: "18px", color: "#6366f1" }} />
|
||||
</div>
|
||||
<div className="flex-1 min-w-0">
|
||||
<h4 className="text-gray-900 font-semibold text-sm m-0">Missing a provider?</h4>
|
||||
<p className="text-gray-500 text-xs m-0 mt-0.5">
|
||||
The LiteLLM engineering team is constantly adding support for new LLM models, providers, endpoints. If you don't see the one you need, let us know and we'll prioritize it.
|
||||
The LiteLLM engineering team is constantly adding support for new LLM models, providers, endpoints. If
|
||||
you don't see the one you need, let us know and we'll prioritize it.
|
||||
</p>
|
||||
</div>
|
||||
<a
|
||||
|
|
@ -294,8 +295,19 @@ const ModelsAndEndpointsView: React.FC<ModelDashboardProps> = ({ premiumUser, te
|
|||
className="flex-shrink-0 inline-flex items-center gap-2 px-4 py-2 bg-[#6366f1] hover:bg-[#5558e3] text-white text-sm font-medium rounded-lg transition-colors"
|
||||
>
|
||||
Request Provider
|
||||
<svg xmlns="http://www.w3.org/2000/svg" className="h-4 w-4" fill="none" viewBox="0 0 24 24" stroke="currentColor" strokeWidth={2}>
|
||||
<path strokeLinecap="round" strokeLinejoin="round" d="M10 6H6a2 2 0 00-2 2v10a2 2 0 002 2h10a2 2 0 002-2v-4M14 4h6m0 0v6m0-6L10 14" />
|
||||
<svg
|
||||
xmlns="http://www.w3.org/2000/svg"
|
||||
className="h-4 w-4"
|
||||
fill="none"
|
||||
viewBox="0 0 24 24"
|
||||
stroke="currentColor"
|
||||
strokeWidth={2}
|
||||
>
|
||||
<path
|
||||
strokeLinecap="round"
|
||||
strokeLinejoin="round"
|
||||
d="M10 6H6a2 2 0 00-2 2v10a2 2 0 002 2h10a2 2 0 002-2v-4M14 4h6m0 0v6m0-6L10 14"
|
||||
/>
|
||||
</svg>
|
||||
</a>
|
||||
</div>
|
||||
|
|
|
|||
|
|
@ -0,0 +1,185 @@
|
|||
import { Form } from "antd";
|
||||
import { act, fireEvent, screen, waitFor } from "@testing-library/react";
|
||||
import { renderWithProviders } from "../../../../../../tests/test-utils";
|
||||
import { afterEach, describe, expect, it, vi } from "vitest";
|
||||
import BaseSSOSettingsForm, { renderProviderFields } from "./BaseSSOSettingsForm";
|
||||
|
||||
describe("BaseSSOSettingsForm", () => {
|
||||
afterEach(() => {
|
||||
vi.clearAllMocks();
|
||||
});
|
||||
|
||||
it("should render", () => {
|
||||
const TestWrapper = () => {
|
||||
const [form] = Form.useForm();
|
||||
const handleSubmit = vi.fn();
|
||||
|
||||
return <BaseSSOSettingsForm form={form} onFormSubmit={handleSubmit} />;
|
||||
};
|
||||
|
||||
renderWithProviders(<TestWrapper />);
|
||||
|
||||
expect(screen.getByText("SSO Provider")).toBeInTheDocument();
|
||||
expect(screen.getByText("Proxy Admin Email")).toBeInTheDocument();
|
||||
expect(screen.getByText("Proxy Base URL")).toBeInTheDocument();
|
||||
});
|
||||
|
||||
it("should render provider fields when provider is selected", async () => {
|
||||
const TestWrapper = () => {
|
||||
const [form] = Form.useForm();
|
||||
const handleSubmit = vi.fn();
|
||||
|
||||
return <BaseSSOSettingsForm form={form} onFormSubmit={handleSubmit} />;
|
||||
};
|
||||
|
||||
renderWithProviders(<TestWrapper />);
|
||||
|
||||
const providerSelect = screen.getByLabelText("SSO Provider");
|
||||
await act(async () => {
|
||||
fireEvent.mouseDown(providerSelect);
|
||||
});
|
||||
|
||||
await waitFor(() => {
|
||||
const googleOption = screen.getByText(/google sso/i);
|
||||
fireEvent.click(googleOption);
|
||||
});
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("Google Client ID")).toBeInTheDocument();
|
||||
expect(screen.getByText("Google Client Secret")).toBeInTheDocument();
|
||||
});
|
||||
});
|
||||
|
||||
it("should show role mappings fields for okta provider", async () => {
|
||||
const TestWrapper = () => {
|
||||
const [form] = Form.useForm();
|
||||
const handleSubmit = vi.fn();
|
||||
|
||||
return <BaseSSOSettingsForm form={form} onFormSubmit={handleSubmit} />;
|
||||
};
|
||||
|
||||
renderWithProviders(<TestWrapper />);
|
||||
|
||||
const providerSelect = screen.getByLabelText("SSO Provider");
|
||||
await act(async () => {
|
||||
fireEvent.mouseDown(providerSelect);
|
||||
});
|
||||
|
||||
await waitFor(() => {
|
||||
const oktaOption = screen.getByText(/okta/i);
|
||||
fireEvent.click(oktaOption);
|
||||
});
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("Use Role Mappings")).toBeInTheDocument();
|
||||
});
|
||||
});
|
||||
|
||||
it("should validate proxy base url format", async () => {
|
||||
const TestWrapper = () => {
|
||||
const [form] = Form.useForm();
|
||||
const handleSubmit = vi.fn();
|
||||
|
||||
return <BaseSSOSettingsForm form={form} onFormSubmit={handleSubmit} />;
|
||||
};
|
||||
|
||||
renderWithProviders(<TestWrapper />);
|
||||
|
||||
const urlInput = screen.getByPlaceholderText("https://example.com");
|
||||
await act(async () => {
|
||||
fireEvent.change(urlInput, { target: { value: "invalid-url" } });
|
||||
fireEvent.blur(urlInput);
|
||||
});
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText(/URL must start with http:\/\/ or https:\/\//i)).toBeInTheDocument();
|
||||
});
|
||||
});
|
||||
|
||||
it("should validate proxy base url trailing slash", async () => {
|
||||
const TestWrapper = () => {
|
||||
const [form] = Form.useForm();
|
||||
const handleSubmit = vi.fn();
|
||||
|
||||
return <BaseSSOSettingsForm form={form} onFormSubmit={handleSubmit} />;
|
||||
};
|
||||
|
||||
renderWithProviders(<TestWrapper />);
|
||||
|
||||
const urlInput = screen.getByPlaceholderText("https://example.com");
|
||||
await act(async () => {
|
||||
fireEvent.change(urlInput, { target: { value: "https://example.com/" } });
|
||||
fireEvent.blur(urlInput);
|
||||
});
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText(/URL must not end with a trailing slash/i)).toBeInTheDocument();
|
||||
});
|
||||
});
|
||||
|
||||
it("should show role mappings fields when use_role_mappings is checked for generic provider", async () => {
|
||||
const TestWrapper = () => {
|
||||
const [form] = Form.useForm();
|
||||
const handleSubmit = vi.fn();
|
||||
|
||||
return <BaseSSOSettingsForm form={form} onFormSubmit={handleSubmit} />;
|
||||
};
|
||||
|
||||
renderWithProviders(<TestWrapper />);
|
||||
|
||||
const providerSelect = screen.getByLabelText("SSO Provider");
|
||||
await act(async () => {
|
||||
fireEvent.mouseDown(providerSelect);
|
||||
});
|
||||
|
||||
await waitFor(() => {
|
||||
const genericOption = screen.getByText(/generic sso/i);
|
||||
fireEvent.click(genericOption);
|
||||
});
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("Use Role Mappings")).toBeInTheDocument();
|
||||
});
|
||||
|
||||
const checkbox = screen.getByLabelText("Use Role Mappings");
|
||||
await act(async () => {
|
||||
fireEvent.click(checkbox);
|
||||
});
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("Group Claim")).toBeInTheDocument();
|
||||
expect(screen.getByText("Default Role")).toBeInTheDocument();
|
||||
});
|
||||
});
|
||||
});
|
||||
|
||||
describe("renderProviderFields", () => {
|
||||
it("should return null for unknown provider", () => {
|
||||
const result = renderProviderFields("unknown");
|
||||
expect(result).toBeNull();
|
||||
});
|
||||
|
||||
it("should return fields for google provider", () => {
|
||||
const result = renderProviderFields("google");
|
||||
expect(result).not.toBeNull();
|
||||
expect(result?.length).toBe(2);
|
||||
});
|
||||
|
||||
it("should return fields for microsoft provider", () => {
|
||||
const result = renderProviderFields("microsoft");
|
||||
expect(result).not.toBeNull();
|
||||
expect(result?.length).toBe(3);
|
||||
});
|
||||
|
||||
it("should return fields for okta provider", () => {
|
||||
const result = renderProviderFields("okta");
|
||||
expect(result).not.toBeNull();
|
||||
expect(result?.length).toBe(5);
|
||||
});
|
||||
|
||||
it("should return fields for generic provider", () => {
|
||||
const result = renderProviderFields("generic");
|
||||
expect(result).not.toBeNull();
|
||||
expect(result?.length).toBe(5);
|
||||
});
|
||||
});
|
||||
|
|
@ -0,0 +1,49 @@
|
|||
import { render, screen } from "@testing-library/react";
|
||||
import userEvent from "@testing-library/user-event";
|
||||
import { describe, it, expect, vi } from "vitest";
|
||||
import DurationSelect from "./DurationSelect";
|
||||
|
||||
describe("DurationSelect", () => {
|
||||
it("should render", () => {
|
||||
render(<DurationSelect />);
|
||||
expect(screen.getByRole("combobox")).toBeInTheDocument();
|
||||
});
|
||||
|
||||
it("should render all three duration options", async () => {
|
||||
const user = userEvent.setup();
|
||||
render(<DurationSelect />);
|
||||
|
||||
const select = screen.getByRole("combobox");
|
||||
await user.click(select);
|
||||
|
||||
expect(screen.getByText("Daily")).toBeInTheDocument();
|
||||
expect(screen.getByText("Weekly")).toBeInTheDocument();
|
||||
expect(screen.getByText("Monthly")).toBeInTheDocument();
|
||||
});
|
||||
|
||||
it("should apply className prop", () => {
|
||||
render(<DurationSelect className="test-class" />);
|
||||
const select = screen.getByRole("combobox");
|
||||
expect(select.closest(".test-class")).toBeInTheDocument();
|
||||
});
|
||||
|
||||
it("should call onChange when an option is selected", async () => {
|
||||
const user = userEvent.setup();
|
||||
const onChange = vi.fn();
|
||||
render(<DurationSelect onChange={onChange} />);
|
||||
|
||||
const select = screen.getByRole("combobox");
|
||||
await user.click(select);
|
||||
|
||||
const dailyOption = screen.getByText("Daily");
|
||||
await user.click(dailyOption);
|
||||
|
||||
expect(onChange).toHaveBeenCalledWith("24h", expect.any(Object));
|
||||
});
|
||||
|
||||
it("should accept and pass value prop to Select", () => {
|
||||
render(<DurationSelect value="7d" />);
|
||||
const select = screen.getByRole("combobox");
|
||||
expect(select).toBeInTheDocument();
|
||||
});
|
||||
});
|
||||
|
|
@ -0,0 +1,17 @@
|
|||
import { Select } from "antd";
|
||||
|
||||
interface DurationSelectProps {
|
||||
className?: string;
|
||||
value?: string;
|
||||
onChange?: (value: string) => void;
|
||||
}
|
||||
|
||||
export default function DurationSelect({ className, value, onChange }: DurationSelectProps) {
|
||||
return (
|
||||
<Select className={className} value={value} onChange={onChange}>
|
||||
<Select.Option value="24h">Daily</Select.Option>
|
||||
<Select.Option value="7d">Weekly</Select.Option>
|
||||
<Select.Option value="30d">Monthly</Select.Option>
|
||||
</Select>
|
||||
);
|
||||
}
|
||||
|
|
@ -0,0 +1,138 @@
|
|||
import * as networking from "@/components/networking";
|
||||
import { act, fireEvent, screen, waitFor } from "@testing-library/react";
|
||||
import { renderWithProviders } from "../../../tests/test-utils";
|
||||
import { afterEach, describe, expect, it, vi } from "vitest";
|
||||
import AvailableTeamsPanel from "./available_teams";
|
||||
|
||||
vi.mock("@/components/networking", () => ({
|
||||
availableTeamListCall: vi.fn(),
|
||||
teamMemberAddCall: vi.fn(),
|
||||
}));
|
||||
|
||||
describe("AvailableTeamsPanel", () => {
|
||||
afterEach(() => {
|
||||
vi.clearAllMocks();
|
||||
});
|
||||
|
||||
it("should render", async () => {
|
||||
vi.mocked(networking.availableTeamListCall).mockResolvedValue([]);
|
||||
|
||||
renderWithProviders(<AvailableTeamsPanel accessToken="token-123" userID="user-123" />);
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("Team Name")).toBeInTheDocument();
|
||||
});
|
||||
});
|
||||
|
||||
it("should display teams when available", async () => {
|
||||
const mockTeams = [
|
||||
{
|
||||
team_id: "team-1",
|
||||
team_alias: "Test Team 1",
|
||||
description: "Test Description 1",
|
||||
models: ["gpt-4"],
|
||||
members_with_roles: [{ user_id: "user-1", user_email: "user1@test.com", role: "admin" }],
|
||||
},
|
||||
{
|
||||
team_id: "team-2",
|
||||
team_alias: "Test Team 2",
|
||||
description: "Test Description 2",
|
||||
models: [],
|
||||
members_with_roles: [{ user_id: "user-2", user_email: "user2@test.com", role: "user" }],
|
||||
},
|
||||
];
|
||||
|
||||
vi.mocked(networking.availableTeamListCall).mockResolvedValue(mockTeams);
|
||||
|
||||
renderWithProviders(<AvailableTeamsPanel accessToken="token-123" userID="user-123" />);
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("Test Team 1")).toBeInTheDocument();
|
||||
expect(screen.getByText("Test Team 2")).toBeInTheDocument();
|
||||
});
|
||||
});
|
||||
|
||||
it("should display empty state when no teams are available", async () => {
|
||||
vi.mocked(networking.availableTeamListCall).mockResolvedValue([]);
|
||||
|
||||
renderWithProviders(<AvailableTeamsPanel accessToken="token-123" userID="user-123" />);
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("No available teams to join")).toBeInTheDocument();
|
||||
});
|
||||
});
|
||||
|
||||
it("should call teamMemberAddCall when join team button is clicked", async () => {
|
||||
const mockTeams = [
|
||||
{
|
||||
team_id: "team-1",
|
||||
team_alias: "Test Team 1",
|
||||
description: "Test Description 1",
|
||||
models: ["gpt-4"],
|
||||
members_with_roles: [{ user_id: "user-1", user_email: "user1@test.com", role: "admin" }],
|
||||
},
|
||||
];
|
||||
|
||||
vi.mocked(networking.availableTeamListCall).mockResolvedValue(mockTeams);
|
||||
vi.mocked(networking.teamMemberAddCall).mockResolvedValue({});
|
||||
|
||||
renderWithProviders(<AvailableTeamsPanel accessToken="token-123" userID="user-123" />);
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("Test Team 1")).toBeInTheDocument();
|
||||
});
|
||||
|
||||
const joinButtons = screen.getAllByRole("button", { name: /join team/i });
|
||||
await act(async () => {
|
||||
fireEvent.click(joinButtons[0]);
|
||||
});
|
||||
|
||||
await waitFor(() => {
|
||||
expect(networking.teamMemberAddCall).toHaveBeenCalledWith("token-123", "team-1", {
|
||||
user_id: "user-123",
|
||||
role: "user",
|
||||
});
|
||||
});
|
||||
});
|
||||
|
||||
it("should display All Proxy Models badge when team has no models", async () => {
|
||||
const mockTeams = [
|
||||
{
|
||||
team_id: "team-1",
|
||||
team_alias: "Test Team 1",
|
||||
description: "Test Description 1",
|
||||
models: [],
|
||||
members_with_roles: [{ user_id: "user-1", user_email: "user1@test.com", role: "admin" }],
|
||||
},
|
||||
];
|
||||
|
||||
vi.mocked(networking.availableTeamListCall).mockResolvedValue(mockTeams);
|
||||
|
||||
renderWithProviders(<AvailableTeamsPanel accessToken="token-123" userID="user-123" />);
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("All Proxy Models")).toBeInTheDocument();
|
||||
});
|
||||
});
|
||||
|
||||
it("should display model badges when team has models", async () => {
|
||||
const mockTeams = [
|
||||
{
|
||||
team_id: "team-1",
|
||||
team_alias: "Test Team 1",
|
||||
description: "Test Description 1",
|
||||
models: ["gpt-4", "gpt-3.5-turbo"],
|
||||
members_with_roles: [{ user_id: "user-1", user_email: "user1@test.com", role: "admin" }],
|
||||
},
|
||||
];
|
||||
|
||||
vi.mocked(networking.availableTeamListCall).mockResolvedValue(mockTeams);
|
||||
|
||||
renderWithProviders(<AvailableTeamsPanel accessToken="token-123" userID="user-123" />);
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("gpt-4")).toBeInTheDocument();
|
||||
expect(screen.getByText("gpt-3.5-turbo")).toBeInTheDocument();
|
||||
});
|
||||
});
|
||||
});
|
||||
|
|
@ -0,0 +1,160 @@
|
|||
import * as networking from "@/components/networking";
|
||||
import { act, fireEvent, screen, waitFor } from "@testing-library/react";
|
||||
import { renderWithProviders } from "../../../tests/test-utils";
|
||||
import { afterEach, describe, expect, it, vi } from "vitest";
|
||||
import MemberPermissions from "./member_permissions";
|
||||
|
||||
vi.mock("@/components/networking", () => ({
|
||||
getTeamPermissionsCall: vi.fn(),
|
||||
teamPermissionsUpdateCall: vi.fn(),
|
||||
}));
|
||||
|
||||
describe("MemberPermissions", () => {
|
||||
afterEach(() => {
|
||||
vi.clearAllMocks();
|
||||
});
|
||||
|
||||
it("should render", async () => {
|
||||
vi.mocked(networking.getTeamPermissionsCall).mockResolvedValue({
|
||||
all_available_permissions: ["/key/generate", "/key/list"],
|
||||
team_member_permissions: ["/key/generate"],
|
||||
});
|
||||
|
||||
renderWithProviders(<MemberPermissions teamId="team-123" accessToken="token-123" canEditTeam={true} />);
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("Member Permissions")).toBeInTheDocument();
|
||||
});
|
||||
});
|
||||
|
||||
it("should display permissions table when permissions are available", async () => {
|
||||
vi.mocked(networking.getTeamPermissionsCall).mockResolvedValue({
|
||||
all_available_permissions: ["/key/generate", "/key/list"],
|
||||
team_member_permissions: ["/key/generate"],
|
||||
});
|
||||
|
||||
renderWithProviders(<MemberPermissions teamId="team-123" accessToken="token-123" canEditTeam={true} />);
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("Method")).toBeInTheDocument();
|
||||
expect(screen.getByText("Endpoint")).toBeInTheDocument();
|
||||
expect(screen.getByText("Description")).toBeInTheDocument();
|
||||
expect(screen.getByText("Allow Access")).toBeInTheDocument();
|
||||
});
|
||||
});
|
||||
|
||||
it("should display empty state when no permissions are available", async () => {
|
||||
vi.mocked(networking.getTeamPermissionsCall).mockResolvedValue({
|
||||
all_available_permissions: [],
|
||||
team_member_permissions: [],
|
||||
});
|
||||
|
||||
renderWithProviders(<MemberPermissions teamId="team-123" accessToken="token-123" canEditTeam={true} />);
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("No permissions available")).toBeInTheDocument();
|
||||
});
|
||||
});
|
||||
|
||||
it("should save permissions when save button is clicked", async () => {
|
||||
vi.mocked(networking.getTeamPermissionsCall).mockResolvedValue({
|
||||
all_available_permissions: ["/key/generate", "/key/list"],
|
||||
team_member_permissions: ["/key/generate"],
|
||||
});
|
||||
vi.mocked(networking.teamPermissionsUpdateCall).mockResolvedValue({});
|
||||
|
||||
renderWithProviders(<MemberPermissions teamId="team-123" accessToken="token-123" canEditTeam={true} />);
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("Member Permissions")).toBeInTheDocument();
|
||||
});
|
||||
|
||||
const checkboxes = screen.getAllByRole("checkbox");
|
||||
const unselectedCheckbox = checkboxes.find((cb) => !(cb as HTMLInputElement).checked);
|
||||
|
||||
if (unselectedCheckbox) {
|
||||
await act(async () => {
|
||||
fireEvent.click(unselectedCheckbox);
|
||||
});
|
||||
|
||||
await waitFor(() => {
|
||||
const saveButton = screen.getByRole("button", { name: /save changes/i });
|
||||
expect(saveButton).toBeInTheDocument();
|
||||
});
|
||||
|
||||
const saveButton = screen.getByRole("button", { name: /save changes/i });
|
||||
await act(async () => {
|
||||
fireEvent.click(saveButton);
|
||||
});
|
||||
|
||||
await waitFor(() => {
|
||||
expect(networking.teamPermissionsUpdateCall).toHaveBeenCalledWith(
|
||||
"token-123",
|
||||
"team-123",
|
||||
expect.arrayContaining(["/key/generate", "/key/list"]),
|
||||
);
|
||||
});
|
||||
}
|
||||
});
|
||||
|
||||
it("should not show save button when canEditTeam is false", async () => {
|
||||
vi.mocked(networking.getTeamPermissionsCall).mockResolvedValue({
|
||||
all_available_permissions: ["/key/generate", "/key/list"],
|
||||
team_member_permissions: ["/key/generate"],
|
||||
});
|
||||
|
||||
renderWithProviders(<MemberPermissions teamId="team-123" accessToken="token-123" canEditTeam={false} />);
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("Member Permissions")).toBeInTheDocument();
|
||||
});
|
||||
|
||||
const checkboxes = screen.getAllByRole("checkbox");
|
||||
checkboxes.forEach((checkbox) => {
|
||||
expect(checkbox).toBeDisabled();
|
||||
});
|
||||
|
||||
expect(screen.queryByRole("button", { name: /save changes/i })).not.toBeInTheDocument();
|
||||
});
|
||||
|
||||
it("should handle reset button click", async () => {
|
||||
vi.mocked(networking.getTeamPermissionsCall).mockResolvedValue({
|
||||
all_available_permissions: ["/key/generate", "/key/list"],
|
||||
team_member_permissions: ["/key/generate"],
|
||||
});
|
||||
|
||||
renderWithProviders(<MemberPermissions teamId="team-123" accessToken="token-123" canEditTeam={true} />);
|
||||
|
||||
await waitFor(() => {
|
||||
expect(screen.getByText("Member Permissions")).toBeInTheDocument();
|
||||
});
|
||||
|
||||
const checkboxes = screen.getAllByRole("checkbox");
|
||||
const unselectedCheckbox = checkboxes.find((cb) => !(cb as HTMLInputElement).checked);
|
||||
|
||||
if (unselectedCheckbox) {
|
||||
await act(async () => {
|
||||
fireEvent.click(unselectedCheckbox);
|
||||
});
|
||||
|
||||
await waitFor(() => {
|
||||
const resetButton = screen.getByRole("button", { name: /reset/i });
|
||||
expect(resetButton).toBeInTheDocument();
|
||||
});
|
||||
|
||||
vi.mocked(networking.getTeamPermissionsCall).mockResolvedValueOnce({
|
||||
all_available_permissions: ["/key/generate", "/key/list"],
|
||||
team_member_permissions: ["/key/generate"],
|
||||
});
|
||||
|
||||
const resetButton = screen.getByRole("button", { name: /reset/i });
|
||||
await act(async () => {
|
||||
fireEvent.click(resetButton);
|
||||
});
|
||||
|
||||
await waitFor(() => {
|
||||
expect(networking.getTeamPermissionsCall).toHaveBeenCalledTimes(2);
|
||||
});
|
||||
}
|
||||
});
|
||||
});
|
||||
|
|
@ -0,0 +1,59 @@
|
|||
import { describe, expect, it } from "vitest";
|
||||
import { getMethodForEndpoint, getPermissionInfo, PERMISSION_DESCRIPTIONS } from "./permission_definitions";
|
||||
|
||||
describe("permission_definitions", () => {
|
||||
describe("getMethodForEndpoint", () => {
|
||||
it("should return GET for info endpoints", () => {
|
||||
expect(getMethodForEndpoint("/key/info")).toBe("GET");
|
||||
});
|
||||
|
||||
it("should return GET for list endpoints", () => {
|
||||
expect(getMethodForEndpoint("/key/list")).toBe("GET");
|
||||
});
|
||||
|
||||
it("should return POST for other endpoints", () => {
|
||||
expect(getMethodForEndpoint("/key/generate")).toBe("POST");
|
||||
expect(getMethodForEndpoint("/key/update")).toBe("POST");
|
||||
expect(getMethodForEndpoint("/key/delete")).toBe("POST");
|
||||
});
|
||||
});
|
||||
|
||||
describe("getPermissionInfo", () => {
|
||||
it("should return correct info for exact match permission", () => {
|
||||
const result = getPermissionInfo("/key/generate");
|
||||
expect(result.method).toBe("POST");
|
||||
expect(result.endpoint).toBe("/key/generate");
|
||||
expect(result.description).toBe(PERMISSION_DESCRIPTIONS["/key/generate"]);
|
||||
expect(result.route).toBe("/key/generate");
|
||||
});
|
||||
|
||||
it("should return GET method for info endpoint", () => {
|
||||
const result = getPermissionInfo("/key/info");
|
||||
expect(result.method).toBe("GET");
|
||||
expect(result.endpoint).toBe("/key/info");
|
||||
expect(result.description).toBe(PERMISSION_DESCRIPTIONS["/key/info"]);
|
||||
});
|
||||
|
||||
it("should return GET method for list endpoint", () => {
|
||||
const result = getPermissionInfo("/key/list");
|
||||
expect(result.method).toBe("GET");
|
||||
expect(result.endpoint).toBe("/key/list");
|
||||
expect(result.description).toBe(PERMISSION_DESCRIPTIONS["/key/list"]);
|
||||
});
|
||||
|
||||
it("should find partial match for permission with pattern", () => {
|
||||
const result = getPermissionInfo("/key/service-account/generate");
|
||||
expect(result.method).toBe("POST");
|
||||
expect(result.endpoint).toBe("/key/service-account/generate");
|
||||
expect(result.description).toBe(PERMISSION_DESCRIPTIONS["/key/service-account/generate"]);
|
||||
});
|
||||
|
||||
it("should return fallback description for unknown permission", () => {
|
||||
const result = getPermissionInfo("/unknown/endpoint");
|
||||
expect(result.method).toBe("POST");
|
||||
expect(result.endpoint).toBe("/unknown/endpoint");
|
||||
expect(result.description).toBe("Access /unknown/endpoint");
|
||||
expect(result.route).toBe("/unknown/endpoint");
|
||||
});
|
||||
});
|
||||
});
|
||||
|
|
@ -48,6 +48,7 @@ import EditLoggingSettings from "./EditLoggingSettings";
|
|||
import MemberModal from "./EditMembership";
|
||||
import MemberPermissions from "./member_permissions";
|
||||
import TeamMembersComponent from "./team_member_view";
|
||||
import DurationSelect from "../common_components/DurationSelect";
|
||||
|
||||
export interface TeamMembership {
|
||||
user_id: string;
|
||||
|
|
@ -413,6 +414,7 @@ const TeamInfoView: React.FC<TeamInfoProps> = ({
|
|||
};
|
||||
|
||||
updateData.max_budget = mapEmptyStringToNull(updateData.max_budget);
|
||||
updateData.team_member_budget_duration = values.team_member_budget_duration;
|
||||
|
||||
if (values.team_member_budget !== undefined) {
|
||||
updateData.team_member_budget = Number(values.team_member_budget);
|
||||
|
|
@ -650,6 +652,8 @@ const TeamInfoView: React.FC<TeamInfoProps> = ({
|
|||
budget_duration: info.budget_duration,
|
||||
team_member_tpm_limit: info.team_member_budget_table?.tpm_limit,
|
||||
team_member_rpm_limit: info.team_member_budget_table?.rpm_limit,
|
||||
team_member_budget: info.team_member_budget_table?.max_budget,
|
||||
team_member_budget_duration: info.team_member_budget_table?.budget_duration,
|
||||
guardrails: info.metadata?.guardrails || [],
|
||||
disable_global_guardrails: info.metadata?.disable_global_guardrails || false,
|
||||
metadata: info.metadata
|
||||
|
|
@ -747,6 +751,13 @@ const TeamInfoView: React.FC<TeamInfoProps> = ({
|
|||
<NumericalInput step={0.01} precision={2} style={{ width: "100%" }} />
|
||||
</Form.Item>
|
||||
|
||||
<Form.Item label="Team Member Budget Duration" name="team_member_budget_duration">
|
||||
<DurationSelect
|
||||
onChange={(value) => form.setFieldValue("team_member_budget_duration", value)}
|
||||
value={form.getFieldValue("team_member_budget_duration")}
|
||||
/>
|
||||
</Form.Item>
|
||||
|
||||
<Form.Item
|
||||
label="Team Member Key Duration (eg: 1d, 1mo)"
|
||||
name="team_member_key_duration"
|
||||
|
|
@ -991,6 +1002,7 @@ const TeamInfoView: React.FC<TeamInfoProps> = ({
|
|||
</Tooltip>
|
||||
</Text>
|
||||
<div>Max Budget: {info.team_member_budget_table?.max_budget || "No Limit"}</div>
|
||||
<div>Budget Duration: {info.team_member_budget_table?.budget_duration || "No Limit"}</div>
|
||||
<div>Key Duration: {info.metadata?.team_member_key_duration || "No Limit"}</div>
|
||||
<div>TPM Limit: {info.team_member_budget_table?.tpm_limit || "No Limit"}</div>
|
||||
<div>RPM Limit: {info.team_member_budget_table?.rpm_limit || "No Limit"}</div>
|
||||
|
|
|
|||
Loading…
Add table
Reference in a new issue