mirror of
https://github.com/BerriAI/litellm.git
synced 2026-10-10 03:28:53 +00:00
Merge branch 'BerriAI:main' into main
This commit is contained in:
 Monesh Ram
GitHub
commit
77e983ab73
672 changed files with 16853 additions and 5750 deletions
|
|
@ -1456,6 +1456,7 @@ jobs:
|
|||
pip install "respx==0.22.0"
|
||||
pip install "pydantic==2.10.2"
|
||||
pip install "boto3==1.36.0"
|
||||
pip install "semantic_router==0.1.10"
|
||||
# Run pytest and generate JUnit XML report
|
||||
- run:
|
||||
name: Run tests
|
||||
|
|
|
|||
37
.github/workflows/check_duplicate_issues.yml
vendored
37
.github/workflows/check_duplicate_issues.yml
vendored
|
|
@ -20,32 +20,29 @@ jobs:
|
|||
ANTHROPIC_API_KEY: ${{ secrets.LITELLM_VIRTUAL_KEY }}
|
||||
ANTHROPIC_BASE_URL: ${{ secrets.LITELLM_BASE_URL }}
|
||||
GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
|
||||
run: |
|
||||
claude -p \
|
||||
--model sonnet \
|
||||
--max-turns 10 \
|
||||
--allowedTools "Bash(gh issue *)" \
|
||||
"A new issue has been created in the ${{ github.repository }} repository.
|
||||
PROMPT: |
|
||||
A new issue has been created in the ${{ github.repository }} repository.
|
||||
|
||||
Issue number: ${{ github.event.issue.number }}
|
||||
Issue number: ${{ github.event.issue.number }}
|
||||
|
||||
Lookup this issue with gh issue view ${{ github.event.issue.number }} --repo ${{ github.repository }}.
|
||||
Lookup this issue with gh issue view ${{ github.event.issue.number }} --repo ${{ github.repository }}.
|
||||
|
||||
Search through existing issues (excluding #${{ github.event.issue.number }}) to find potential duplicates.
|
||||
Search through existing issues (excluding #${{ github.event.issue.number }}) to find potential duplicates.
|
||||
|
||||
Use gh issue list --repo ${{ github.repository }} with relevant search terms from the new issue's title and description. Try multiple keyword combinations to search broadly. Check both open and recently closed issues.
|
||||
Use gh issue list --repo ${{ github.repository }} with relevant search terms from the new issue's title and description. Try multiple keyword combinations to search broadly. Check both open and recently closed issues.
|
||||
|
||||
Consider:
|
||||
1. Similar titles or descriptions
|
||||
2. Same error messages or symptoms
|
||||
3. Related functionality or components
|
||||
4. Similar feature requests
|
||||
Consider:
|
||||
1. Similar titles or descriptions
|
||||
2. Same error messages or symptoms
|
||||
3. Related functionality or components
|
||||
4. Similar feature requests
|
||||
|
||||
If you find potential duplicates, post a SINGLE comment on issue #${{ github.event.issue.number }} using gh issue comment ${{ github.event.issue.number }} --repo ${{ github.repository }} with this format:
|
||||
If you find potential duplicates, post a SINGLE comment on issue #${{ github.event.issue.number }} using gh issue comment ${{ github.event.issue.number }} --repo ${{ github.repository }} with this format:
|
||||
|
||||
_This comment was generated by an LLM and may be inaccurate._
|
||||
_This comment was generated by an LLM and may be inaccurate._
|
||||
|
||||
This issue might be a duplicate of existing issues. Please check:
|
||||
- #[issue_number]: [brief description of similarity]
|
||||
This issue might be a duplicate of existing issues. Please check:
|
||||
- #[issue_number]: [brief description of similarity]
|
||||
|
||||
If you find NO duplicates, do NOT post any comment. Stay silent."
|
||||
If you find NO duplicates, do NOT post any comment. Stay silent.
|
||||
run: claude -p "$PROMPT" --model sonnet --max-turns 10 --allowedTools "Bash(gh issue *)"
|
||||
|
|
|
|||
37
.github/workflows/check_duplicate_prs.yml
vendored
37
.github/workflows/check_duplicate_prs.yml
vendored
|
|
@ -24,32 +24,29 @@ jobs:
|
|||
ANTHROPIC_API_KEY: ${{ secrets.LITELLM_VIRTUAL_KEY }}
|
||||
ANTHROPIC_BASE_URL: ${{ secrets.LITELLM_BASE_URL }}
|
||||
GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
|
||||
run: |
|
||||
claude -p \
|
||||
--model sonnet \
|
||||
--max-turns 10 \
|
||||
--allowedTools "Bash(gh pr *)" \
|
||||
"A new PR has been opened in the ${{ github.repository }} repository.
|
||||
PROMPT: |
|
||||
A new PR has been opened in the ${{ github.repository }} repository.
|
||||
|
||||
PR number: ${{ github.event.pull_request.number }}
|
||||
PR number: ${{ github.event.pull_request.number }}
|
||||
|
||||
Lookup this PR with gh pr view ${{ github.event.pull_request.number }} --repo ${{ github.repository }}.
|
||||
Lookup this PR with gh pr view ${{ github.event.pull_request.number }} --repo ${{ github.repository }}.
|
||||
|
||||
Search through existing open PRs (excluding #${{ github.event.pull_request.number }}) to find potential duplicates.
|
||||
Search through existing open PRs (excluding #${{ github.event.pull_request.number }}) to find potential duplicates.
|
||||
|
||||
Use gh pr list --repo ${{ github.repository }} with relevant search terms from the new PR's title and description. Try multiple keyword combinations to search broadly. Check both open and recently closed PRs.
|
||||
Use gh pr list --repo ${{ github.repository }} with relevant search terms from the new PR's title and description. Try multiple keyword combinations to search broadly. Check both open and recently closed PRs.
|
||||
|
||||
Consider:
|
||||
1. Similar titles or descriptions
|
||||
2. Same bug fix or feature being implemented
|
||||
3. Related functionality or components
|
||||
4. Overlapping code changes (same files or areas)
|
||||
Consider:
|
||||
1. Similar titles or descriptions
|
||||
2. Same bug fix or feature being implemented
|
||||
3. Related functionality or components
|
||||
4. Overlapping code changes (same files or areas)
|
||||
|
||||
If you find potential duplicates, post a SINGLE comment on PR #${{ github.event.pull_request.number }} using gh pr comment ${{ github.event.pull_request.number }} --repo ${{ github.repository }} with this format:
|
||||
If you find potential duplicates, post a SINGLE comment on PR #${{ github.event.pull_request.number }} using gh pr comment ${{ github.event.pull_request.number }} --repo ${{ github.repository }} with this format:
|
||||
|
||||
_This comment was generated by an LLM and may be inaccurate._
|
||||
_This comment was generated by an LLM and may be inaccurate._
|
||||
|
||||
This PR might be a duplicate of existing PRs. Please check:
|
||||
- #[pr_number]: [brief description of similarity]
|
||||
This PR might be a duplicate of existing PRs. Please check:
|
||||
- #[pr_number]: [brief description of similarity]
|
||||
|
||||
If you find NO duplicates, do NOT post any comment. Stay silent."
|
||||
If you find NO duplicates, do NOT post any comment. Stay silent.
|
||||
run: claude -p "$PROMPT" --model sonnet --max-turns 10 --allowedTools "Bash(gh pr *)"
|
||||
|
|
|
|||
|
|
@ -158,6 +158,8 @@ run_grype_scans() {
|
|||
"CVE-2025-11468" # No fix available yet
|
||||
"CVE-2026-1299" # Python 3.13 email module header injection - not applicable, LiteLLM doesn't use BytesGenerator for email serialization
|
||||
"CVE-2026-0775" # npm cli incorrect permission assignment - no fix available yet, npm is only used at build/prisma-generate time
|
||||
"GHSA-3ppc-4f35-3m26" # minimatch ReDoS via repeated wildcards - from nodejs_wheel bundled npm, not used in application runtime code
|
||||
"GHSA-83g3-92jg-28cx" # tar arbitrary file read/write via hardlink - from nodejs_wheel bundled npm, not used in application runtime code
|
||||
)
|
||||
|
||||
# Build JSON array of allowlisted CVE IDs for jq
|
||||
|
|
|
|||
154
docs/my-website/blog/server_root_path/index.md
Normal file
154
docs/my-website/blog/server_root_path/index.md
Normal file
|
|
@ -0,0 +1,154 @@
|
|||
---
|
||||
slug: server-root-path-incident
|
||||
title: "Incident Report: SERVER_ROOT_PATH regression broke UI routing"
|
||||
date: 2026-02-21T10:00:00
|
||||
authors:
|
||||
- name: Yuneng Jiang
|
||||
title: SWE @ LiteLLM (Full Stack)
|
||||
url: https://www.linkedin.com/in/yunengjiang/
|
||||
- name: Ishaan Jaff
|
||||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
- name: Krrish Dholakia
|
||||
title: "CEO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
tags: [incident-report, ui, stability]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
**Date:** January 22, 2026
|
||||
**Duration:** ~4 days (until fix merged January 26, 2026)
|
||||
**Severity:** High
|
||||
**Status:** Resolved
|
||||
|
||||
> **Note:** This fix is available starting from LiteLLM `v1.81.3.rc.6` or higher.
|
||||
|
||||
## Summary
|
||||
|
||||
A PR ([`#19467`](https://github.com/BerriAI/litellm/pull/19467)) accidentally removed the `root_path=server_root_path` parameter from the FastAPI app initialization in `proxy_server.py`. This caused the proxy to ignore the `SERVER_ROOT_PATH` environment variable when serving the UI. Users who deploy LiteLLM behind a reverse proxy with a path prefix (e.g., `/api/v1` or `/llmproxy`) found that all UI pages returned 404 Not Found.
|
||||
|
||||
- **LLM API calls:** No impact. API routing was unaffected.
|
||||
- **UI pages:** All UI pages returned 404 for deployments using `SERVER_ROOT_PATH`.
|
||||
- **Swagger/OpenAPI docs:** Broken when accessed through the configured root path.
|
||||
|
||||
{/* truncate */}
|
||||
|
||||
---
|
||||
|
||||
## Background
|
||||
|
||||
Many LiteLLM deployments run behind a reverse proxy (e.g., Nginx, Traefik, AWS ALB) that routes traffic to LiteLLM under a path prefix. FastAPI's `root_path` parameter tells the application about this prefix so it can correctly serve static files, generate URLs, and handle routing.
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant User as User Browser
|
||||
participant RP as Reverse Proxy
|
||||
participant LP as LiteLLM Proxy
|
||||
|
||||
User->>RP: GET /llmproxy/ui/
|
||||
RP->>LP: GET /ui/ (X-Forwarded-Prefix: /llmproxy)
|
||||
|
||||
Note over LP: Before regression:<br/>FastAPI root_path="/llmproxy"<br/>→ Serves UI correctly
|
||||
|
||||
Note over LP: After regression:<br/>FastAPI root_path=""<br/>→ UI assets resolve to wrong paths<br/>→ 404 Not Found
|
||||
```
|
||||
|
||||
The `root_path` parameter was present in `proxy_server.py` since early versions of LiteLLM. It was removed as a side effect of PR [#19467](https://github.com/BerriAI/litellm/pull/19467), which was intended to fix a different UI 404 issue.
|
||||
|
||||
---
|
||||
|
||||
## Root cause
|
||||
|
||||
PR [#19467](https://github.com/BerriAI/litellm/pull/19467) (`73d49f8`) removed the `root_path=server_root_path` line from the `FastAPI()` constructor in `proxy_server.py`:
|
||||
|
||||
```diff
|
||||
app = FastAPI(
|
||||
docs_url=_get_docs_url(),
|
||||
redoc_url=_get_redoc_url(),
|
||||
title=_title,
|
||||
description=_description,
|
||||
version=version,
|
||||
- root_path=server_root_path,
|
||||
lifespan=proxy_startup_event,
|
||||
)
|
||||
```
|
||||
|
||||
Without `root_path`, FastAPI treated all requests as if the application was mounted at `/`, causing path mismatches for any deployment using `SERVER_ROOT_PATH`.
|
||||
|
||||
The regression went undetected because:
|
||||
|
||||
1. **No automated test** verified that `root_path` was set on the FastAPI app.
|
||||
2. **No manual test procedure** existed for `SERVER_ROOT_PATH` functionality.
|
||||
3. **Default deployments** (without `SERVER_ROOT_PATH`) were unaffected, so most CI tests passed.
|
||||
|
||||
---
|
||||
|
||||
## Remediation
|
||||
|
||||
| # | Action | Status | Code |
|
||||
| --- | ------------------------------------------------------------------------------------------------- | ------- | -------------------------------------------------------------------------------------------------------------------------- |
|
||||
| 1 | Restore `root_path=server_root_path` in FastAPI app initialization | ✅ Done | [`#19790`](https://github.com/BerriAI/litellm/pull/19790) (`5426b3c`) |
|
||||
| 2 | Add unit tests for `get_server_root_path()` and FastAPI app initialization | ✅ Done | [`test_server_root_path.py`](https://github.com/BerriAI/litellm/blob/main/tests/proxy_unit_tests/test_server_root_path.py) |
|
||||
| 3 | Add CI workflow that builds Docker image and tests UI routing with `SERVER_ROOT_PATH` on every PR | ✅ Done | [`test_server_root_path.yml`](https://github.com/BerriAI/litellm/blob/main/.github/workflows/test_server_root_path.yml) |
|
||||
| 4 | Document manual test procedure for `SERVER_ROOT_PATH` | ✅ Done | [Discussion #8495](https://github.com/BerriAI/litellm/discussions/8495) |
|
||||
|
||||
---
|
||||
|
||||
## CI workflow details
|
||||
|
||||
The new [`test_server_root_path.yml`](https://github.com/BerriAI/litellm/blob/main/.github/workflows/test_server_root_path.yml) workflow runs on every PR against `main`. It:
|
||||
|
||||
1. Builds the LiteLLM Docker image
|
||||
2. Starts a container with `SERVER_ROOT_PATH` set (tests both `/api/v1` and `/llmproxy`)
|
||||
3. Verifies the UI returns valid HTML at `{ROOT_PATH}/ui/`
|
||||
4. Fails the workflow if the UI is unreachable
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
A["PR opened/updated"] --> B["Build Docker image"]
|
||||
B --> C["Start container with SERVER_ROOT_PATH=/api/v1"]
|
||||
B --> D["Start container with SERVER_ROOT_PATH=/llmproxy"]
|
||||
C --> E["curl {ROOT_PATH}/ui/ → expect HTML"]
|
||||
D --> F["curl {ROOT_PATH}/ui/ → expect HTML"]
|
||||
E -->|"HTML found"| G["✅ Pass"]
|
||||
E -->|"404 or no HTML"| H["❌ Fail Workflow"]
|
||||
F -->|"HTML found"| G
|
||||
F -->|"404 or no HTML"| H
|
||||
|
||||
style G fill:#d4edda,stroke:#28a745
|
||||
style H fill:#f8d7da,stroke:#dc3545
|
||||
```
|
||||
|
||||
This prevents future regressions where changes to `proxy_server.py` accidentally break `SERVER_ROOT_PATH` support.
|
||||
|
||||
---
|
||||
|
||||
## Timeline
|
||||
|
||||
| Time (UTC) | Event |
|
||||
| ------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------ |
|
||||
| Jan 22, 2026 04:20 | PR [#19467](https://github.com/BerriAI/litellm/pull/19467) merged, removing `root_path=server_root_path` |
|
||||
| Jan 22–26 | Users on nightly builds report UI 404 errors when using `SERVER_ROOT_PATH` |
|
||||
| Jan 26, 2026 17:48 | Fix PR [#19790](https://github.com/BerriAI/litellm/pull/19790) merged, restoring `root_path=server_root_path` |
|
||||
| Feb 18, 2026 | CI workflow [`test_server_root_path.yml`](https://github.com/BerriAI/litellm/blob/main/.github/workflows/test_server_root_path.yml) added to run on every PR |
|
||||
|
||||
---
|
||||
|
||||
## Resolution steps for users
|
||||
|
||||
For users still experiencing issues, update to the latest LiteLLM version:
|
||||
|
||||
```bash
|
||||
pip install --upgrade litellm
|
||||
```
|
||||
|
||||
Verify your `SERVER_ROOT_PATH` is correctly set:
|
||||
|
||||
```bash
|
||||
# In your environment or docker-compose.yml
|
||||
SERVER_ROOT_PATH="/your-prefix"
|
||||
```
|
||||
|
||||
Then confirm the UI is accessible at `http://your-host:4000/your-prefix/ui/`.
|
||||
|
|
@ -219,3 +219,189 @@ curl -X POST http://localhost:4000/v1/chat/completions \
|
|||
3. If a route's similarity score exceeds the threshold, the request is routed to that model
|
||||
4. If no route matches, the request goes to the default model
|
||||
|
||||
---
|
||||
|
||||
## Complexity Router
|
||||
|
||||
The Complexity Router provides an alternative to semantic routing that uses **rule-based scoring** to classify requests by complexity and route them to appropriate models — with **zero external API calls** and **sub-millisecond latency**.
|
||||
|
||||
### When to Use
|
||||
|
||||
| Feature | Semantic Auto Router | Complexity Router |
|
||||
|---------|---------------------|-------------------|
|
||||
| Classification | Embedding-based matching | Rule-based scoring |
|
||||
| Latency | ~100-500ms (embedding API) | <1ms |
|
||||
| API Calls | Requires embedding model | None |
|
||||
| Training | Requires utterance examples | Works out of the box |
|
||||
| Best For | Intent-based routing | Cost optimization |
|
||||
|
||||
Use **Complexity Router** when you want to:
|
||||
- Route simple queries to cheaper/faster models (e.g., gpt-4o-mini)
|
||||
- Route complex queries to more capable models (e.g., claude-sonnet-4)
|
||||
- Minimize latency overhead from routing decisions
|
||||
- Avoid additional API costs for embeddings
|
||||
|
||||
### LiteLLM Python SDK
|
||||
|
||||
```python
|
||||
from litellm import Router
|
||||
|
||||
router = Router(
|
||||
model_list=[
|
||||
# Target models for each tier
|
||||
{
|
||||
"model_name": "gpt-4o-mini",
|
||||
"litellm_params": {"model": "gpt-4o-mini"},
|
||||
},
|
||||
{
|
||||
"model_name": "gpt-4o",
|
||||
"litellm_params": {"model": "gpt-4o"},
|
||||
},
|
||||
{
|
||||
"model_name": "claude-sonnet",
|
||||
"litellm_params": {"model": "claude-sonnet-4-20250514"},
|
||||
},
|
||||
{
|
||||
"model_name": "o1-preview",
|
||||
"litellm_params": {"model": "o1-preview"},
|
||||
},
|
||||
# Complexity router configuration
|
||||
{
|
||||
"model_name": "smart-router",
|
||||
"litellm_params": {
|
||||
"model": "auto_router/complexity_router",
|
||||
"complexity_router_config": {
|
||||
"tiers": {
|
||||
"SIMPLE": "gpt-4o-mini",
|
||||
"MEDIUM": "gpt-4o",
|
||||
"COMPLEX": "claude-sonnet",
|
||||
"REASONING": "o1-preview",
|
||||
},
|
||||
},
|
||||
"complexity_router_default_model": "gpt-4o",
|
||||
},
|
||||
},
|
||||
],
|
||||
)
|
||||
```
|
||||
|
||||
#### Usage
|
||||
|
||||
```python
|
||||
# Simple query → routes to gpt-4o-mini
|
||||
response = await router.acompletion(
|
||||
model="smart-router",
|
||||
messages=[{"role": "user", "content": "What is 2+2?"}],
|
||||
)
|
||||
|
||||
# Complex technical query → routes to claude-sonnet or higher
|
||||
response = await router.acompletion(
|
||||
model="smart-router",
|
||||
messages=[{"role": "user", "content": "Design a distributed microservice architecture with Kubernetes orchestration"}],
|
||||
)
|
||||
|
||||
# Reasoning request → routes to o1-preview
|
||||
response = await router.acompletion(
|
||||
model="smart-router",
|
||||
messages=[{"role": "user", "content": "Think step by step and reason through this problem carefully..."}],
|
||||
)
|
||||
```
|
||||
|
||||
### LiteLLM Proxy Server
|
||||
|
||||
Add the complexity router to your `config.yaml`:
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
# Target models
|
||||
- model_name: gpt-4o-mini
|
||||
litellm_params:
|
||||
model: gpt-4o-mini
|
||||
|
||||
- model_name: gpt-4o
|
||||
litellm_params:
|
||||
model: gpt-4o
|
||||
|
||||
- model_name: claude-sonnet
|
||||
litellm_params:
|
||||
model: claude-sonnet-4-20250514
|
||||
|
||||
- model_name: o1-preview
|
||||
litellm_params:
|
||||
model: o1-preview
|
||||
|
||||
# Complexity router
|
||||
- model_name: smart-router
|
||||
litellm_params:
|
||||
model: auto_router/complexity_router
|
||||
complexity_router_config:
|
||||
tiers:
|
||||
SIMPLE: gpt-4o-mini
|
||||
MEDIUM: gpt-4o
|
||||
COMPLEX: claude-sonnet
|
||||
REASONING: o1-preview
|
||||
complexity_router_default_model: gpt-4o
|
||||
```
|
||||
|
||||
### Configuration Options
|
||||
|
||||
#### Tier Boundaries
|
||||
|
||||
Customize the score thresholds for each tier:
|
||||
|
||||
```yaml
|
||||
complexity_router_config:
|
||||
tiers:
|
||||
SIMPLE: gpt-4o-mini
|
||||
MEDIUM: gpt-4o
|
||||
COMPLEX: claude-sonnet
|
||||
REASONING: o1-preview
|
||||
tier_boundaries:
|
||||
simple_medium: 0.15 # Below 0.15 → SIMPLE
|
||||
medium_complex: 0.35 # 0.15-0.35 → MEDIUM
|
||||
complex_reasoning: 0.60 # 0.35-0.60 → COMPLEX, above → REASONING
|
||||
```
|
||||
|
||||
#### Token Thresholds
|
||||
|
||||
Adjust when prompts are considered "short" or "long":
|
||||
|
||||
```yaml
|
||||
complexity_router_config:
|
||||
token_thresholds:
|
||||
simple: 15 # Prompts under 15 tokens are penalized (simple indicator)
|
||||
complex: 400 # Prompts over 400 tokens get complexity boost
|
||||
```
|
||||
|
||||
#### Dimension Weights
|
||||
|
||||
Customize how much each signal contributes to the complexity score:
|
||||
|
||||
```yaml
|
||||
complexity_router_config:
|
||||
dimension_weights:
|
||||
tokenCount: 0.10 # Prompt length
|
||||
codePresence: 0.30 # Code-related keywords
|
||||
reasoningMarkers: 0.25 # "step by step", "think through", etc.
|
||||
technicalTerms: 0.25 # Domain-specific complexity
|
||||
simpleIndicators: 0.05 # "what is", "define", greetings
|
||||
multiStepPatterns: 0.03 # "first...then", numbered steps
|
||||
questionComplexity: 0.02 # Multiple questions
|
||||
```
|
||||
|
||||
### How Complexity Routing Works
|
||||
|
||||
The router scores each request across 7 dimensions:
|
||||
|
||||
| Dimension | What It Detects | Effect |
|
||||
|-----------|-----------------|--------|
|
||||
| Token Count | Short (<15) or long (>400) prompts | Short = simple, long = complex |
|
||||
| Code Presence | "function", "class", "api", "database", etc. | Increases complexity |
|
||||
| Reasoning Markers | "step by step", "think through", "analyze" | Triggers REASONING tier |
|
||||
| Technical Terms | "architecture", "distributed", "encryption" | Increases complexity |
|
||||
| Simple Indicators | "what is", "define", "hello" | Decreases complexity |
|
||||
| Multi-Step Patterns | "first...then", "1. 2. 3." | Increases complexity |
|
||||
| Question Complexity | Multiple question marks | Increases complexity |
|
||||
|
||||
**Special behavior:** If 2+ reasoning markers are detected in the user message, the request automatically routes to the REASONING tier regardless of the weighted score.
|
||||
|
||||
|
|
|
|||
|
|
@ -574,6 +574,8 @@ router_settings:
|
|||
| DEFAULT_REASONING_EFFORT_MINIMAL_THINKING_BUDGET_GEMINI_2_5_PRO | Default minimal reasoning effort thinking budget for Gemini 2.5 Pro. Default is 512
|
||||
| DEFAULT_REDIS_MAJOR_VERSION | Default Redis major version to assume when version cannot be determined. Default is 7
|
||||
| DEFAULT_REDIS_SYNC_INTERVAL | Default Redis synchronization interval in seconds. Default is 1
|
||||
| DEFAULT_SEMANTIC_GUARD_EMBEDDING_MODEL | Default embedding model for Semantic Guard (route-matching guardrail). Default is "text-embedding-3-small"
|
||||
| DEFAULT_SEMANTIC_GUARD_SIMILARITY_THRESHOLD | Default similarity threshold for Semantic Guard route matching. Default is 0.75
|
||||
| DEFAULT_REPLICATE_GPU_PRICE_PER_SECOND | Default price per second for Replicate GPU. Default is 0.001400
|
||||
| DEFAULT_REPLICATE_POLLING_DELAY_SECONDS | Default delay in seconds for Replicate polling. Default is 1
|
||||
| DEFAULT_REPLICATE_POLLING_RETRIES | Default number of retries for Replicate polling. Default is 5
|
||||
|
|
@ -756,6 +758,7 @@ router_settings:
|
|||
| LITELLM_CLI_JWT_EXPIRATION_HOURS | Expiration time in hours for CLI-generated JWT tokens. Default is 24 hours
|
||||
| LITELLM_DD_AGENT_HOST | Hostname or IP of DataDog agent for LiteLLM-specific logging. When set, logs are sent to agent instead of direct API
|
||||
| LITELLM_DEPLOYMENT_ENVIRONMENT | Environment name for the deployment (e.g., "production", "staging"). Used as a fallback when OTEL_ENVIRONMENT_NAME is not set. Sets the `environment` tag in telemetry data
|
||||
| LITELLM_DETAILED_TIMING | When true, adds detailed per-phase timing headers to responses (`x-litellm-timing-{pre-processing,llm-api,post-processing,message-copy}-ms`). Default is false. See [latency overhead docs](../troubleshoot/latency_overhead.md)
|
||||
| LITELLM_DD_AGENT_PORT | Port of DataDog agent for LiteLLM-specific log intake. Default is 10518
|
||||
| LITELLM_DD_LLM_OBS_PORT | Port for Datadog LLM Observability agent. Default is 8126
|
||||
| LITELLM_DONT_SHOW_FEEDBACK_BOX | Flag to hide feedback box in LiteLLM UI
|
||||
|
|
@ -807,6 +810,7 @@ router_settings:
|
|||
| LOGGING_WORKER_MAX_QUEUE_SIZE | Maximum size of the logging worker queue. When the queue is full, the worker aggressively clears tasks to make room instead of dropping logs. Default is 50,000
|
||||
| LOGGING_WORKER_MAX_TIME_PER_COROUTINE | Maximum time in seconds allowed for each coroutine in the logging worker before timing out. Default is 20.0
|
||||
| LOGGING_WORKER_CLEAR_PERCENTAGE | Percentage of the queue to extract when clearing. Default is 50%
|
||||
| MAX_BASE64_LENGTH_FOR_LOGGING | Maximum number of base64 characters to keep in logging payloads. Data URIs exceeding this are replaced with a size placeholder. Set to 0 to disable truncation. Default is 64
|
||||
| MAX_COMPETITOR_NAMES | Maximum number of competitor names allowed in policy template enrichment. Default is 100
|
||||
| MAX_EXCEPTION_MESSAGE_LENGTH | Maximum length for exception messages. Default is 2000
|
||||
| MAX_ITERATIONS_TO_CLEAR_QUEUE | Maximum number of iterations to attempt when clearing the logging worker queue during shutdown. Default is 200
|
||||
|
|
@ -830,6 +834,7 @@ router_settings:
|
|||
| MAX_LANGFUSE_INITIALIZED_CLIENTS | Maximum number of Langfuse clients to initialize on proxy. Default is 50. This is set since langfuse initializes 1 thread everytime a client is initialized. We've had an incident in the past where we reached 100% cpu utilization because Langfuse was initialized several times.
|
||||
| MAX_MCP_SEMANTIC_FILTER_TOOLS_HEADER_LENGTH | Maximum header length for MCP semantic filter tools. Default is 150
|
||||
| MAX_POLICY_ESTIMATE_IMPACT_ROWS | Maximum number of rows returned when estimating the impact of a policy. Default is 1000
|
||||
| MAX_PAYLOAD_SIZE_FOR_DEBUG_LOG | Maximum payload size in bytes for full DEBUG serialization. Payloads exceeding this will be truncated in logs. Default is 102400 (100 KB)
|
||||
| MIN_NON_ZERO_TEMPERATURE | Minimum non-zero temperature value. Default is 0.0001
|
||||
| MINIMUM_PROMPT_CACHE_TOKEN_COUNT | Minimum token count for caching a prompt. Default is 1024
|
||||
| MISTRAL_API_BASE | Base URL for Mistral API. Default is https://api.mistral.ai
|
||||
|
|
@ -893,6 +898,13 @@ router_settings:
|
|||
| POSTHOG_API_URL | Base URL for PostHog API (defaults to https://us.i.posthog.com)
|
||||
| POSTHOG_MOCK | Enable mock mode for PostHog integration testing. When set to true, intercepts PostHog API calls and returns mock responses without making actual network calls. Default is false
|
||||
| POSTHOG_MOCK_LATENCY_MS | Mock latency in milliseconds for PostHog API calls when mock mode is enabled. Simulates network round-trip time. Default is 100ms
|
||||
| PRISMA_AUTH_RECONNECT_LOCK_TIMEOUT_SECONDS | Lock timeout in seconds for Prisma auth reconnection. Default is 0.1
|
||||
| PRISMA_AUTH_RECONNECT_TIMEOUT_SECONDS | Timeout in seconds for Prisma auth reconnection attempts. Default is 2.0
|
||||
| PRISMA_HEALTH_WATCHDOG_ENABLED | Enable the Prisma DB health watchdog that monitors and reconnects on connection loss. Default is true
|
||||
| PRISMA_HEALTH_WATCHDOG_INTERVAL_SECONDS | Interval in seconds for Prisma health watchdog probes. Default is 30
|
||||
| PRISMA_HEALTH_WATCHDOG_PROBE_TIMEOUT_SECONDS | Timeout in seconds for each Prisma health probe. Default is 5.0
|
||||
| PRISMA_RECONNECT_COOLDOWN_SECONDS | Cooldown in seconds between Prisma reconnection attempts. Default is 15
|
||||
| PRISMA_WATCHDOG_RECONNECT_TIMEOUT_SECONDS | Timeout in seconds for Prisma watchdog-initiated reconnection. Default is 30.0
|
||||
| PREDIBASE_API_BASE | Base URL for Predibase API
|
||||
| PRESIDIO_ANALYZER_API_BASE | Base URL for Presidio Analyzer service
|
||||
| PRESIDIO_ANONYMIZER_API_BASE | Base URL for Presidio Anonymizer service
|
||||
|
|
|
|||
92
docs/my-website/docs/proxy/ui_store_model_db_setting.md
Normal file
92
docs/my-website/docs/proxy/ui_store_model_db_setting.md
Normal file
|
|
@ -0,0 +1,92 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Store Model in DB Settings
|
||||
|
||||
Enable or disable storing model definitions in the database directly from the Admin UI—no config file edits or proxy restart required. This is especially useful for cloud deployments where updating the config is difficult or requires a long release process.
|
||||
|
||||
## Overview
|
||||
|
||||
Previously, the `store_model_in_db` setting had to be configured in `proxy_config.yaml` under `general_settings`. Changing it required editing the config and restarting the proxy, which was problematic for cloud users who don't have direct access to the config file or who want to avoid the downtime caused by restarts.
|
||||
|
||||
<Image img={require('../../img/ui_store_model_in_db.png')} />
|
||||
|
||||
**Store Model in DB Settings** lets you:
|
||||
|
||||
- **Enable or disable storing models in the database** – Control whether model definitions are cached in your database (useful for reducing config file size and improving scalability)
|
||||
- **Apply changes immediately** – No proxy restart needed; settings take effect for new model operations as soon as you save
|
||||
|
||||
:::warning UI overrides config
|
||||
Settings changed in the UI **override** the values in your config file. For example, if `store_model_in_db` is set to `false` in `general_settings`, enabling it in the UI will still persist model definitions to the database. Use the UI when you want runtime control without redeploying.
|
||||
:::
|
||||
|
||||
## How Store Model in DB Works
|
||||
|
||||
When `store_model_in_db` is enabled, the LiteLLM proxy stores model definitions in the database instead of relying solely on your `proxy_config.yaml`. This provides several benefits:
|
||||
|
||||
- **Reduced config size** – Move model definitions out of YAML for easier maintenance
|
||||
- **Scalability** – Database storage scales better than large YAML files
|
||||
- **Dynamic updates** – Models can be added or updated without editing config files
|
||||
- **Persistence** – Model definitions persist across proxy instances and restarts
|
||||
|
||||
The setting applies to all new model operations from the moment you save it.
|
||||
|
||||
## How to Configure Store Model in DB in the UI
|
||||
|
||||
### 1. Access Models + Endpoints Settings
|
||||
|
||||
Navigate to the Admin UI (e.g. `http://localhost:4000/ui` or your `PROXY_BASE_URL/ui`) and go to the **Models + Endpoints** page.
|
||||
|
||||
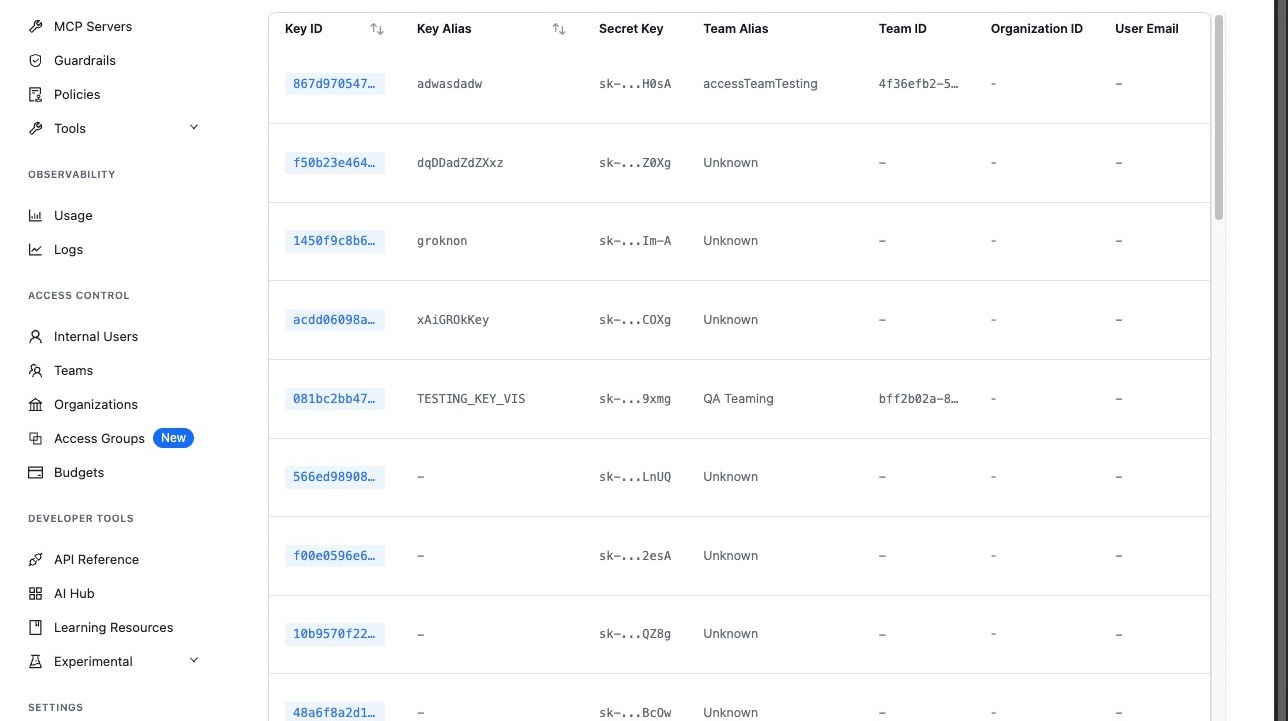
|
||||
|
||||
### 2. Open Settings
|
||||
|
||||
Click **Models + Endpoints** from the navigation menu.
|
||||
|
||||
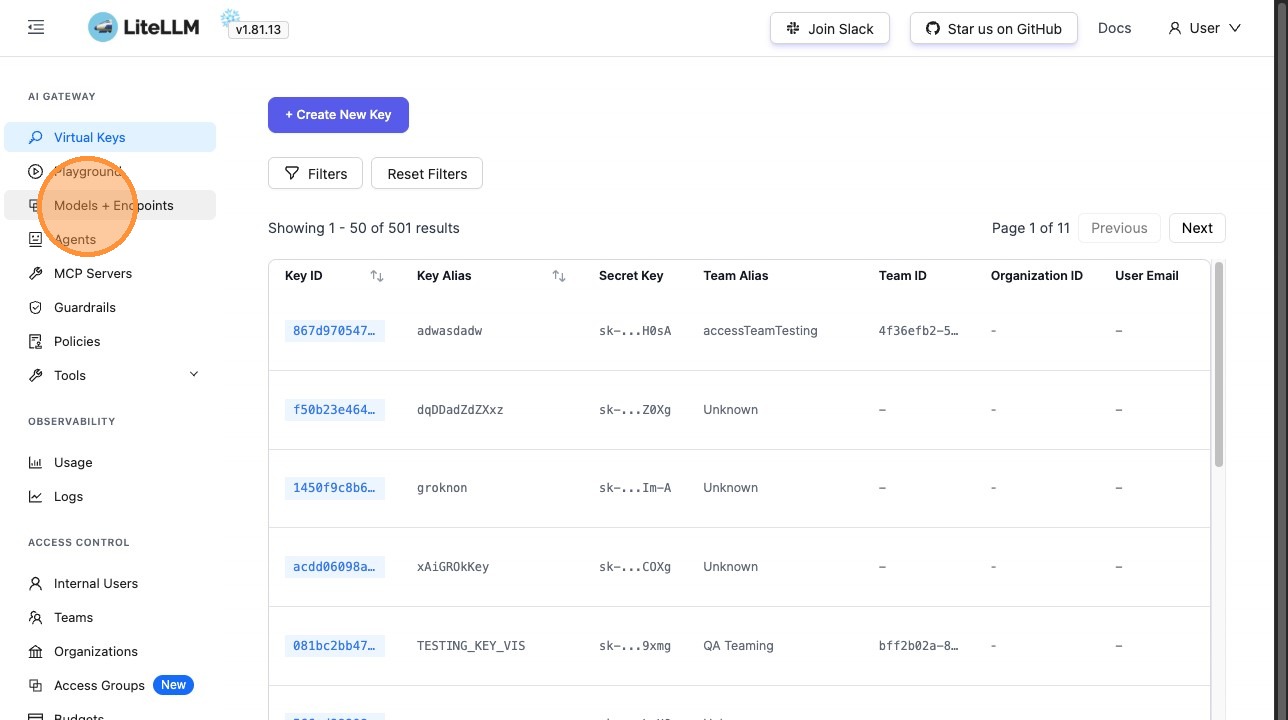
|
||||
|
||||
### 3. Click the Settings Icon
|
||||
|
||||
Look for the settings (gear) icon on the Models + Endpoints page to open the configuration panel.
|
||||
|
||||
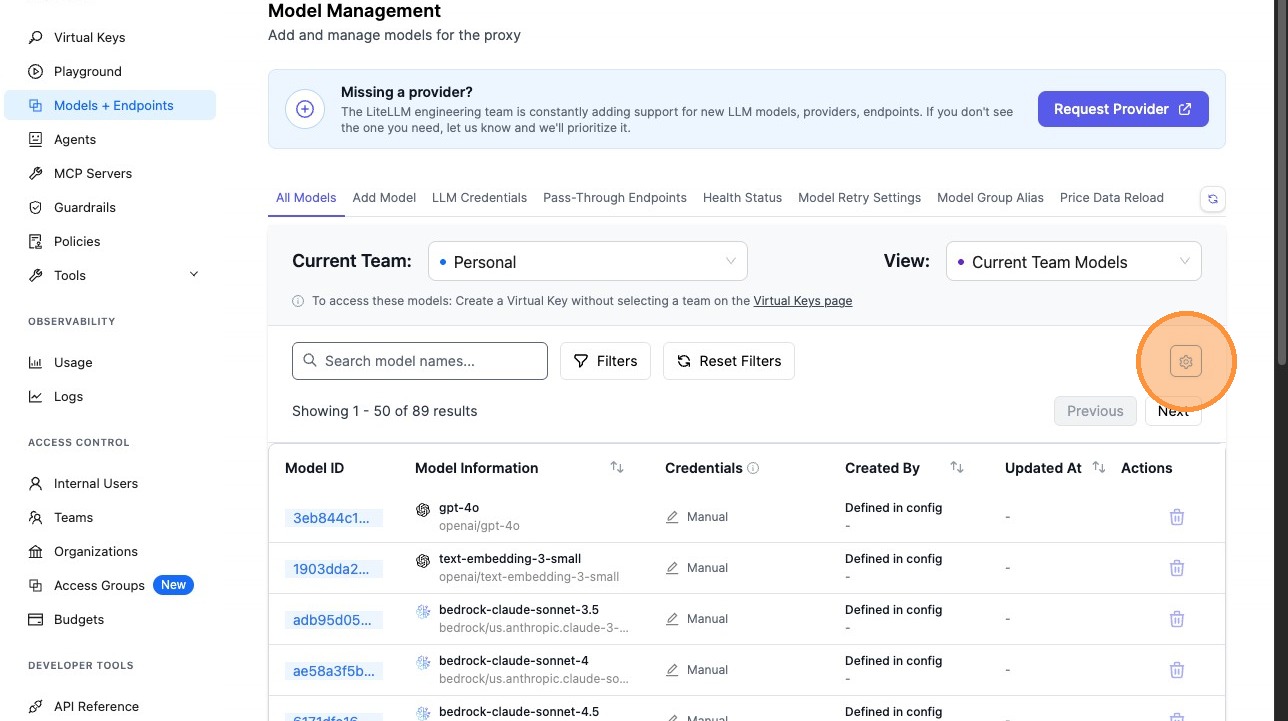
|
||||
|
||||
### 4. Enable or Disable Store Model in DB
|
||||
|
||||
Toggle the **Store Model in DB** setting based on your preference:
|
||||
|
||||
- **Enabled**: Model definitions will be stored in the database
|
||||
- **Disabled**: Models are read from the config file only
|
||||
|
||||
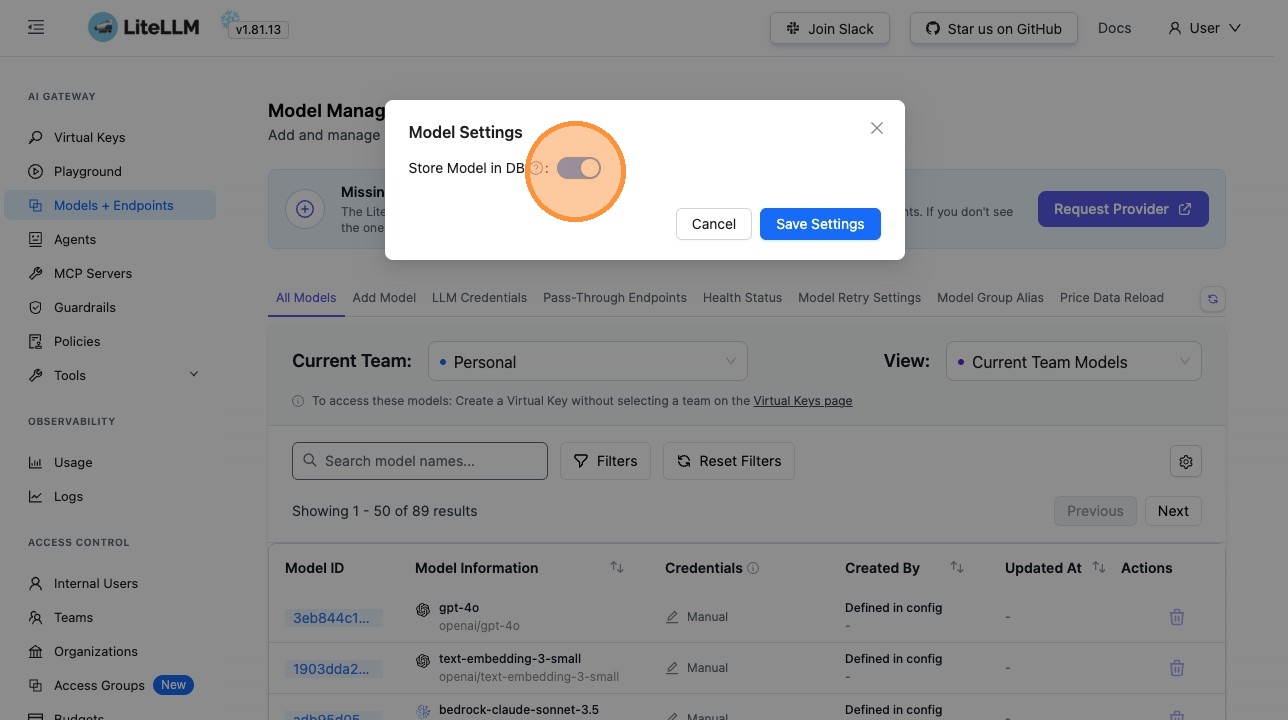
|
||||
|
||||
### 5. Save Settings
|
||||
|
||||
Click **Save Settings** to apply the change. No proxy restart is required; the new setting takes effect immediately for subsequent model operations.
|
||||
|
||||
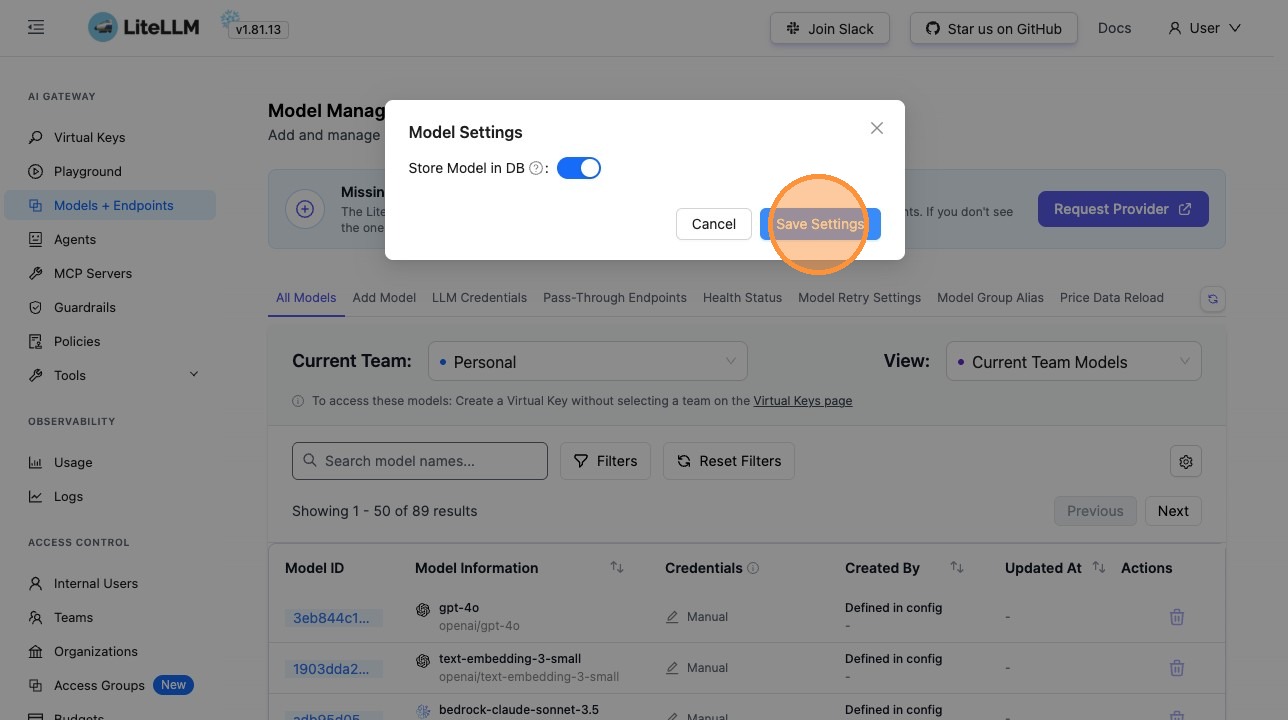
|
||||
|
||||
## Use Cases
|
||||
|
||||
### Cloud and Managed Deployments
|
||||
|
||||
When the proxy runs in a managed or cloud environment, config may be in a separate repo, require a long release cycle, or be controlled by another team. Using the UI lets you change the `store_model_in_db` setting without going through a deployment process.
|
||||
|
||||
### Reducing Configuration Complexity
|
||||
|
||||
For large deployments with hundreds of models, storing model definitions in the database reduces the size and complexity of your `proxy_config.yaml`, making it easier to maintain and version control.
|
||||
|
||||
### Dynamic Model Management
|
||||
|
||||
Enable `store_model_in_db` to support dynamic model additions and updates without editing your config file. Teams can manage models through the UI or API without needing to redeploy the proxy.
|
||||
|
||||
### Zero-Downtime Updates
|
||||
|
||||
Change the setting from the UI and have it take effect immediately—perfect for production environments where downtime must be minimized.
|
||||
|
||||
## Related Documentation
|
||||
|
||||
- [Admin UI Overview](./ui_overview.md) – General guide to the LiteLLM Admin UI
|
||||
- [Models and Endpoints](./models_and_endpoints.md) – Managing models and API endpoints
|
||||
- [Config Settings](./config_settings.md) – `store_model_in_db` in `general_settings`
|
||||
|
|
@ -887,7 +887,8 @@ router = litellm.Router(
|
|||
# `responses_api_deployment_check` ensures Requests with `previous_response_id`
|
||||
# are routed to the same deployment. `deployment_affinity` adds sticky sessions
|
||||
# for requests without `previous_response_id` (useful for implicit caching).
|
||||
optional_pre_call_checks=["responses_api_deployment_check", "deployment_affinity"],
|
||||
# `session_affinity` adds sticky sessions based on `session_id` metadata.
|
||||
optional_pre_call_checks=["responses_api_deployment_check", "deployment_affinity", "session_affinity"],
|
||||
# Optional (default is 3600 seconds / 1 hour)
|
||||
deployment_affinity_ttl_seconds=3600,
|
||||
)
|
||||
|
|
@ -919,10 +920,12 @@ follow_up = await router.aresponses(
|
|||
To enable session continuity for Responses API in your LiteLLM proxy, set `optional_pre_call_checks` in your proxy config.yaml.
|
||||
|
||||
- `responses_api_deployment_check`: high priority routing when `previous_response_id` is provided
|
||||
- `session_affinity`: sticky sessions based on session id (takes priority over `deployment_affinity`)
|
||||
- `deployment_affinity`: sticky sessions based on user key (applies even without `previous_response_id`)
|
||||
|
||||
Notes:
|
||||
- User-key affinity is keyed on `metadata.user_api_key_hash` (the API key hash). The OpenAI `user` request parameter is an end-user identifier and is intentionally not used for deployment affinity.
|
||||
- Session-ID affinity is keyed on `metadata.session_id`. For proxy requests, this can be passed via the `x-litellm-session-id` HTTP header. For Python SDK requests, you can pass it via `litellm_metadata={"session_id": "value"}` in request args.
|
||||
- `user_api_key_hash` is already SHA-256, and is used as-is (no double hashing).
|
||||
- Affinity is scoped by a stable model identifier (the model-map key, e.g. `model_map_information.model_map_key`) so model aliases map to the same stickiness bucket.
|
||||
- The mapping TTL is controlled by `deployment_affinity_ttl_seconds` (configured on Router init / proxy startup).
|
||||
|
|
@ -945,6 +948,7 @@ model_list:
|
|||
router_settings:
|
||||
optional_pre_call_checks:
|
||||
- responses_api_deployment_check
|
||||
- session_affinity
|
||||
- deployment_affinity
|
||||
# Optional (default is 3600 seconds / 1 hour)
|
||||
deployment_affinity_ttl_seconds: 3600
|
||||
|
|
|
|||
210
docs/my-website/docs/tutorials/openclaw_integration.md
Normal file
210
docs/my-website/docs/tutorials/openclaw_integration.md
Normal file
|
|
@ -0,0 +1,210 @@
|
|||
---
|
||||
sidebar_label: "OpenClaw"
|
||||
---
|
||||
|
||||
# OpenClaw + LiteLLM Integration
|
||||
|
||||
[OpenClaw](https://openclaw.ai) is a self-hosted AI assistant that connects chat apps (WhatsApp, Telegram, Discord, and more) to LLM providers. By routing OpenClaw through LiteLLM Proxy, you get access to 100+ providers, cost tracking, spend limits, and automatic failover — all from a single gateway.
|
||||
|
||||
## What you'll set up
|
||||
|
||||
```
|
||||
Chat apps → OpenClaw Gateway → LiteLLM Proxy → LLM Providers (OpenAI, Anthropic, etc.)
|
||||
```
|
||||
|
||||
## Prerequisites
|
||||
|
||||
| Requirement | How to get it |
|
||||
|---|---|
|
||||
| **Node.js 22+** | `node --version` — install from [nodejs.org](https://nodejs.org) if needed |
|
||||
| **Python 3.8+** | `python --version` |
|
||||
| **At least one LLM API key** | OpenAI, Anthropic, Gemini, etc. |
|
||||
|
||||
## Step 1 — Install LiteLLM Proxy
|
||||
|
||||
```bash
|
||||
pip install 'litellm[proxy]'
|
||||
```
|
||||
|
||||
## Step 2 — Create a LiteLLM config file
|
||||
|
||||
Create a config file `litellm_config.yaml` with the models you want to use. Here's an example with OpenAI:
|
||||
|
||||
```yaml title="litellm_config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4o
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
general_settings:
|
||||
master_key: sk-your-secret-key # pick any value — this is YOUR proxy password
|
||||
```
|
||||
|
||||
:::tip Multi-provider example
|
||||
You can add as many models as you want from different providers:
|
||||
|
||||
```yaml title="litellm_config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4o
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
- model_name: claude-sonnet
|
||||
litellm_params:
|
||||
model: anthropic/claude-sonnet-4-20250514
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
|
||||
- model_name: gemini-flash
|
||||
litellm_params:
|
||||
model: gemini/gemini-2.0-flash
|
||||
api_key: os.environ/GEMINI_API_KEY
|
||||
|
||||
general_settings:
|
||||
master_key: sk-your-secret-key
|
||||
```
|
||||
|
||||
See [LiteLLM proxy config docs](https://docs.litellm.ai/docs/proxy/configs) for all options.
|
||||
:::
|
||||
|
||||
## Step 3 — Start the proxy
|
||||
|
||||
Make sure your API key(s) are available as environment variables (via `export`, `.env` file, or however you manage secrets), then start the proxy:
|
||||
|
||||
```bash
|
||||
litellm --config litellm_config.yaml --port 4000
|
||||
```
|
||||
|
||||
## Step 4 — Install OpenClaw
|
||||
|
||||
```bash
|
||||
# macOS / Linux
|
||||
curl -fsSL https://openclaw.ai/install.sh | bash
|
||||
```
|
||||
|
||||
:::note Windows
|
||||
On Windows, use PowerShell: `iwr -useb https://openclaw.ai/install.ps1 | iex`
|
||||
|
||||
WSL2 is recommended over native Windows.
|
||||
:::
|
||||
|
||||
## Step 5 — Connect OpenClaw to LiteLLM
|
||||
|
||||
Run the onboarding wizard:
|
||||
|
||||
```bash
|
||||
openclaw onboard --install-daemon
|
||||
```
|
||||
|
||||
When prompted:
|
||||
|
||||
1. Choose **QuickStart** or **Manual** as the onboarding mode (both work — Manual gives you more options for gateway settings)
|
||||
2. Select **LiteLLM** as the model/auth provider
|
||||
3. Enter your LiteLLM `master_key` from Step 2 and set the base URL to your proxy address (e.g., `http://localhost:4000`)
|
||||
4. When asked for the default model, choose **Enter model manually** and type the model name from your `litellm_config.yaml` (e.g., `litellm/gpt-4o`)
|
||||
|
||||
You can also set or change the model after onboarding:
|
||||
|
||||
```bash
|
||||
openclaw models set litellm/gpt-4o
|
||||
```
|
||||
|
||||
For scripted / CI environments, you can skip the prompts entirely:
|
||||
|
||||
```bash
|
||||
openclaw onboard --non-interactive --accept-risk \
|
||||
--auth-choice litellm-api-key \
|
||||
--litellm-api-key "sk-your-secret-key" \
|
||||
--custom-base-url "http://localhost:4000" \
|
||||
--install-daemon --skip-channels --skip-skills
|
||||
```
|
||||
|
||||
## Step 6 — Verify
|
||||
|
||||
Check the gateway is healthy:
|
||||
|
||||
```bash
|
||||
openclaw health
|
||||
```
|
||||
|
||||
Then send a test message:
|
||||
|
||||
```bash
|
||||
openclaw dashboard # web UI
|
||||
openclaw tui # terminal UI
|
||||
openclaw agent --agent main -m "Hello, what model are you?" # one-shot CLI
|
||||
```
|
||||
|
||||
If you get a response from your model, the integration is working.
|
||||
|
||||
Check which model is active:
|
||||
|
||||
```bash
|
||||
openclaw models status
|
||||
```
|
||||
|
||||
## Config reference
|
||||
|
||||
After onboarding, OpenClaw stores the LiteLLM provider config in `~/.openclaw/openclaw.json`. The relevant sections are something like this:
|
||||
|
||||
```json5 title="~/.openclaw/openclaw.json (excerpt)"
|
||||
{
|
||||
"models": {
|
||||
"providers": {
|
||||
"litellm": {
|
||||
"baseUrl": "http://localhost:4000",
|
||||
"apiKey": "sk-your-secret-key",
|
||||
"api": "openai-completions",
|
||||
"models": [
|
||||
{
|
||||
"id": "gpt-4o",
|
||||
"name": "GPT-4o via LiteLLM"
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
},
|
||||
"agents": {
|
||||
"defaults": {
|
||||
"model": { "primary": "litellm/gpt-4o" }
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
You can edit this file directly to add more models or change the `baseUrl`. OpenClaw hot-reloads changes automatically.
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
**Connection refused / proxy not reachable**
|
||||
|
||||
Make sure the LiteLLM proxy is running and that the `baseUrl` in your OpenClaw config matches:
|
||||
|
||||
```bash
|
||||
curl http://localhost:4000/health -H "Authorization: Bearer sk-your-secret-key"
|
||||
```
|
||||
|
||||
**Wrong model or "Invalid model name"**
|
||||
|
||||
The model name in OpenClaw must match a `model_name` from your `litellm_config.yaml`. Switch the active model with:
|
||||
|
||||
```bash
|
||||
openclaw models set litellm/gpt-4o
|
||||
```
|
||||
|
||||
**Gateway pairing issues after reinstall**
|
||||
|
||||
If the CLI can't connect to the gateway after a reinstall, stop the service and reinstall it:
|
||||
|
||||
```bash
|
||||
openclaw gateway stop
|
||||
openclaw gateway install
|
||||
```
|
||||
|
||||
## References
|
||||
|
||||
- [OpenClaw docs](https://docs.openclaw.ai)
|
||||
- [OpenClaw LiteLLM provider docs](https://docs.openclaw.ai/providers/litellm)
|
||||
- [OpenClaw model providers](https://docs.openclaw.ai/concepts/model-providers)
|
||||
- [LiteLLM proxy configuration](https://docs.litellm.ai/docs/proxy/configs)
|
||||
BIN
docs/my-website/img/release_notes/compliance_playground.png
Normal file
BIN
docs/my-website/img/release_notes/compliance_playground.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 780 KiB |
BIN
docs/my-website/img/release_notes/guardrail_garden.png
Normal file
BIN
docs/my-website/img/release_notes/guardrail_garden.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 1.2 MiB |
BIN
docs/my-website/img/ui_store_model_in_db.png
Normal file
BIN
docs/my-website/img/ui_store_model_in_db.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 234 KiB |
159
docs/my-website/package-lock.json
generated
159
docs/my-website/package-lock.json
generated
|
|
@ -8339,9 +8339,9 @@
|
|||
}
|
||||
},
|
||||
"node_modules/ajv": {
|
||||
"version": "8.17.1",
|
||||
"resolved": "https://registry.npmjs.org/ajv/-/ajv-8.17.1.tgz",
|
||||
"integrity": "sha512-B/gBuNg5SiMTrPkC+A2+cW0RszwxYmn6VYxB/inlBStS5nx6xHIt/ehKRhIMhqusl7a8LjQoZnjCs5vhwxOQ1g==",
|
||||
"version": "8.18.0",
|
||||
"resolved": "https://registry.npmjs.org/ajv/-/ajv-8.18.0.tgz",
|
||||
"integrity": "sha512-PlXPeEWMXMZ7sPYOHqmDyCJzcfNrUr3fGNKtezX14ykXOEIvyK81d+qydx89KY5O71FKMPaQ2vBfBFI5NHR63A==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"fast-deep-equal": "^3.1.3",
|
||||
|
|
@ -8721,10 +8721,13 @@
|
|||
}
|
||||
},
|
||||
"node_modules/balanced-match": {
|
||||
"version": "1.0.2",
|
||||
"resolved": "https://registry.npmjs.org/balanced-match/-/balanced-match-1.0.2.tgz",
|
||||
"integrity": "sha512-3oSeUO0TMV67hN1AmbXsK4yaqU7tjiHlbxRDZOpH0KW9+CeX4bRAaX0Anxt0tx2MrpRpWwQaPwIlISEJhYU5Pw==",
|
||||
"license": "MIT"
|
||||
"version": "4.0.3",
|
||||
"resolved": "https://registry.npmjs.org/balanced-match/-/balanced-match-4.0.3.tgz",
|
||||
"integrity": "sha512-1pHv8LX9CpKut1Zp4EXey7Z8OfH11ONNH6Dhi2WDUt31VVZFXZzKwXcysBgqSumFCmR+0dqjMK5v5JiFHzi0+g==",
|
||||
"license": "MIT",
|
||||
"engines": {
|
||||
"node": "20 || >=22"
|
||||
}
|
||||
},
|
||||
"node_modules/bare-events": {
|
||||
"version": "2.8.2",
|
||||
|
|
@ -8838,12 +8841,15 @@
|
|||
"license": "MIT"
|
||||
},
|
||||
"node_modules/baseline-browser-mapping": {
|
||||
"version": "2.8.30",
|
||||
"resolved": "https://registry.npmjs.org/baseline-browser-mapping/-/baseline-browser-mapping-2.8.30.tgz",
|
||||
"integrity": "sha512-aTUKW4ptQhS64+v2d6IkPzymEzzhw+G0bA1g3uBRV3+ntkH+svttKseW5IOR4Ed6NUVKqnY7qT3dKvzQ7io4AA==",
|
||||
"version": "2.10.0",
|
||||
"resolved": "https://registry.npmjs.org/baseline-browser-mapping/-/baseline-browser-mapping-2.10.0.tgz",
|
||||
"integrity": "sha512-lIyg0szRfYbiy67j9KN8IyeD7q7hcmqnJ1ddWmNt19ItGpNN64mnllmxUNFIOdOm6by97jlL6wfpTTJrmnjWAA==",
|
||||
"license": "Apache-2.0",
|
||||
"bin": {
|
||||
"baseline-browser-mapping": "dist/cli.js"
|
||||
"baseline-browser-mapping": "dist/cli.cjs"
|
||||
},
|
||||
"engines": {
|
||||
"node": ">=6.0.0"
|
||||
}
|
||||
},
|
||||
"node_modules/batch": {
|
||||
|
|
@ -9024,13 +9030,15 @@
|
|||
}
|
||||
},
|
||||
"node_modules/brace-expansion": {
|
||||
"version": "1.1.12",
|
||||
"resolved": "https://registry.npmjs.org/brace-expansion/-/brace-expansion-1.1.12.tgz",
|
||||
"integrity": "sha512-9T9UjW3r0UW5c1Q7GTwllptXwhvYmEzFhzMfZ9H7FQWt+uZePjZPjBP/W1ZEyZ1twGWom5/56TF4lPcqjnDHcg==",
|
||||
"version": "5.0.2",
|
||||
"resolved": "https://registry.npmjs.org/brace-expansion/-/brace-expansion-5.0.2.tgz",
|
||||
"integrity": "sha512-Pdk8c9poy+YhOgVWw1JNN22/HcivgKWwpxKq04M/jTmHyCZn12WPJebZxdjSa5TmBqISrUSgNYU3eRORljfCCw==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"balanced-match": "^1.0.0",
|
||||
"concat-map": "0.0.1"
|
||||
"balanced-match": "^4.0.2"
|
||||
},
|
||||
"engines": {
|
||||
"node": "20 || >=22"
|
||||
}
|
||||
},
|
||||
"node_modules/braces": {
|
||||
|
|
@ -9046,9 +9054,9 @@
|
|||
}
|
||||
},
|
||||
"node_modules/browserslist": {
|
||||
"version": "4.28.0",
|
||||
"resolved": "https://registry.npmjs.org/browserslist/-/browserslist-4.28.0.tgz",
|
||||
"integrity": "sha512-tbydkR/CxfMwelN0vwdP/pLkDwyAASZ+VfWm4EOwlB6SWhx1sYnWLqo8N5j0rAzPfzfRaxt0mM/4wPU/Su84RQ==",
|
||||
"version": "4.28.1",
|
||||
"resolved": "https://registry.npmjs.org/browserslist/-/browserslist-4.28.1.tgz",
|
||||
"integrity": "sha512-ZC5Bd0LgJXgwGqUknZY/vkUQ04r8NXnJZ3yYi4vDmSiZmC/pdSN0NbNRPxZpbtO4uAfDUAFffO8IZoM3Gj8IkA==",
|
||||
"funding": [
|
||||
{
|
||||
"type": "opencollective",
|
||||
|
|
@ -9065,11 +9073,11 @@
|
|||
],
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"baseline-browser-mapping": "^2.8.25",
|
||||
"caniuse-lite": "^1.0.30001754",
|
||||
"electron-to-chromium": "^1.5.249",
|
||||
"baseline-browser-mapping": "^2.9.0",
|
||||
"caniuse-lite": "^1.0.30001759",
|
||||
"electron-to-chromium": "^1.5.263",
|
||||
"node-releases": "^2.0.27",
|
||||
"update-browserslist-db": "^1.1.4"
|
||||
"update-browserslist-db": "^1.2.0"
|
||||
},
|
||||
"bin": {
|
||||
"browserslist": "cli.js"
|
||||
|
|
@ -9262,9 +9270,9 @@
|
|||
}
|
||||
},
|
||||
"node_modules/caniuse-lite": {
|
||||
"version": "1.0.30001756",
|
||||
"resolved": "https://registry.npmjs.org/caniuse-lite/-/caniuse-lite-1.0.30001756.tgz",
|
||||
"integrity": "sha512-4HnCNKbMLkLdhJz3TToeVWHSnfJvPaq6vu/eRP0Ahub/07n484XHhBF5AJoSGHdVrS8tKFauUQz8Bp9P7LVx7A==",
|
||||
"version": "1.0.30001770",
|
||||
"resolved": "https://registry.npmjs.org/caniuse-lite/-/caniuse-lite-1.0.30001770.tgz",
|
||||
"integrity": "sha512-x/2CLQ1jHENRbHg5PSId2sXq1CIO1CISvwWAj027ltMVG2UNgW+w9oH2+HzgEIRFembL8bUlXtfbBHR1fCg2xw==",
|
||||
"funding": [
|
||||
{
|
||||
"type": "opencollective",
|
||||
|
|
@ -9764,12 +9772,6 @@
|
|||
"integrity": "sha512-Tpp60P6IUJDTuOq/5Z8cdskzJujfwqfOTkrwIwj7IRISpnkJnT6SyJ4PCPnGMoFjC9ddhal5KVIYtAt97ix05A==",
|
||||
"license": "MIT"
|
||||
},
|
||||
"node_modules/concat-map": {
|
||||
"version": "0.0.1",
|
||||
"resolved": "https://registry.npmjs.org/concat-map/-/concat-map-0.0.1.tgz",
|
||||
"integrity": "sha512-/Srv4dswyQNBfohGpz9o6Yb3Gz3SrUDqBH5rTuhGR7ahtlbYKnVxw2bCFMRljaA7EXHaXZ8wsHdodFvbkhKmqg==",
|
||||
"license": "MIT"
|
||||
},
|
||||
"node_modules/confbox": {
|
||||
"version": "0.2.2",
|
||||
"resolved": "https://registry.npmjs.org/confbox/-/confbox-0.2.2.tgz",
|
||||
|
|
@ -11413,9 +11415,9 @@
|
|||
"license": "MIT"
|
||||
},
|
||||
"node_modules/electron-to-chromium": {
|
||||
"version": "1.5.259",
|
||||
"resolved": "https://registry.npmjs.org/electron-to-chromium/-/electron-to-chromium-1.5.259.tgz",
|
||||
"integrity": "sha512-I+oLXgpEJzD6Cwuwt1gYjxsDmu/S/Kd41mmLA3O+/uH2pFRO/DvOjUyGozL8j3KeLV6WyZ7ssPwELMsXCcsJAQ==",
|
||||
"version": "1.5.302",
|
||||
"resolved": "https://registry.npmjs.org/electron-to-chromium/-/electron-to-chromium-1.5.302.tgz",
|
||||
"integrity": "sha512-sM6HAN2LyK82IyPBpznDRqlTQAtuSaO+ShzFiWTvoMJLHyZ+Y39r8VMfHzwbU8MVBzQ4Wdn85+wlZl2TLGIlwg==",
|
||||
"license": "ISC"
|
||||
},
|
||||
"node_modules/emoji-regex": {
|
||||
|
|
@ -11468,13 +11470,13 @@
|
|||
}
|
||||
},
|
||||
"node_modules/enhanced-resolve": {
|
||||
"version": "5.18.3",
|
||||
"resolved": "https://registry.npmjs.org/enhanced-resolve/-/enhanced-resolve-5.18.3.tgz",
|
||||
"integrity": "sha512-d4lC8xfavMeBjzGr2vECC3fsGXziXZQyJxD868h2M/mBI3PwAuODxAkLkq5HYuvrPYcUtiLzsTo8U3PgX3Ocww==",
|
||||
"version": "5.19.0",
|
||||
"resolved": "https://registry.npmjs.org/enhanced-resolve/-/enhanced-resolve-5.19.0.tgz",
|
||||
"integrity": "sha512-phv3E1Xl4tQOShqSte26C7Fl84EwUdZsyOuSSk9qtAGyyQs2s3jJzComh+Abf4g187lUUAvH+H26omrqia2aGg==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"graceful-fs": "^4.2.4",
|
||||
"tapable": "^2.2.0"
|
||||
"tapable": "^2.3.0"
|
||||
},
|
||||
"engines": {
|
||||
"node": ">=10.13.0"
|
||||
|
|
@ -11520,9 +11522,9 @@
|
|||
}
|
||||
},
|
||||
"node_modules/es-module-lexer": {
|
||||
"version": "1.7.0",
|
||||
"resolved": "https://registry.npmjs.org/es-module-lexer/-/es-module-lexer-1.7.0.tgz",
|
||||
"integrity": "sha512-jEQoCwk8hyb2AZziIOLhDqpm5+2ww5uIE6lkO/6jcOCusfk6LhMHpXXfBLXTZ7Ydyt0j4VoUQv6uGNYbdW+kBA==",
|
||||
"version": "2.0.0",
|
||||
"resolved": "https://registry.npmjs.org/es-module-lexer/-/es-module-lexer-2.0.0.tgz",
|
||||
"integrity": "sha512-5POEcUuZybH7IdmGsD8wlf0AI55wMecM9rVBTI/qEAy2c1kTOm3DjFYjrBdI2K3BaJjJYfYFeRtM0t9ssnRuxw==",
|
||||
"license": "MIT"
|
||||
},
|
||||
"node_modules/es-object-atoms": {
|
||||
|
|
@ -12142,9 +12144,9 @@
|
|||
}
|
||||
},
|
||||
"node_modules/file-loader/node_modules/ajv": {
|
||||
"version": "6.12.6",
|
||||
"resolved": "https://registry.npmjs.org/ajv/-/ajv-6.12.6.tgz",
|
||||
"integrity": "sha512-j3fVLgvTo527anyYyJOGTYJbG+vnnQYvE0m5mmkc1TK+nxAppkCLMIL0aZ4dblVCNoGShhm+kzE4ZUykBoMg4g==",
|
||||
"version": "6.14.0",
|
||||
"resolved": "https://registry.npmjs.org/ajv/-/ajv-6.14.0.tgz",
|
||||
"integrity": "sha512-IWrosm/yrn43eiKqkfkHis7QioDleaXQHdDVPKg0FSwwd/DuvyX79TZnFOnYpB7dcsFAMmtFztZuXPDvSePkFw==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"fast-deep-equal": "^3.1.1",
|
||||
|
|
@ -16720,15 +16722,18 @@
|
|||
"license": "ISC"
|
||||
},
|
||||
"node_modules/minimatch": {
|
||||
"version": "3.1.2",
|
||||
"resolved": "https://registry.npmjs.org/minimatch/-/minimatch-3.1.2.tgz",
|
||||
"integrity": "sha512-J7p63hRiAjw1NDEww1W7i37+ByIrOWO5XQQAzZ3VOcL0PNybwpfmV/N05zFAzwQ9USyEcX6t3UO+K5aqBQOIHw==",
|
||||
"license": "ISC",
|
||||
"version": "10.2.1",
|
||||
"resolved": "https://registry.npmjs.org/minimatch/-/minimatch-10.2.1.tgz",
|
||||
"integrity": "sha512-MClCe8IL5nRRmawL6ib/eT4oLyeKMGCghibcDWK+J0hh0Q8kqSdia6BvbRMVk6mPa6WqUa5uR2oxt6C5jd533A==",
|
||||
"license": "BlueOak-1.0.0",
|
||||
"dependencies": {
|
||||
"brace-expansion": "^1.1.7"
|
||||
"brace-expansion": "^5.0.2"
|
||||
},
|
||||
"engines": {
|
||||
"node": "*"
|
||||
"node": "20 || >=22"
|
||||
},
|
||||
"funding": {
|
||||
"url": "https://github.com/sponsors/isaacs"
|
||||
}
|
||||
},
|
||||
"node_modules/minimist": {
|
||||
|
|
@ -17021,9 +17026,9 @@
|
|||
}
|
||||
},
|
||||
"node_modules/null-loader/node_modules/ajv": {
|
||||
"version": "6.12.6",
|
||||
"resolved": "https://registry.npmjs.org/ajv/-/ajv-6.12.6.tgz",
|
||||
"integrity": "sha512-j3fVLgvTo527anyYyJOGTYJbG+vnnQYvE0m5mmkc1TK+nxAppkCLMIL0aZ4dblVCNoGShhm+kzE4ZUykBoMg4g==",
|
||||
"version": "6.14.0",
|
||||
"resolved": "https://registry.npmjs.org/ajv/-/ajv-6.14.0.tgz",
|
||||
"integrity": "sha512-IWrosm/yrn43eiKqkfkHis7QioDleaXQHdDVPKg0FSwwd/DuvyX79TZnFOnYpB7dcsFAMmtFztZuXPDvSePkFw==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"fast-deep-equal": "^3.1.1",
|
||||
|
|
@ -19294,9 +19299,9 @@
|
|||
}
|
||||
},
|
||||
"node_modules/qs": {
|
||||
"version": "6.14.1",
|
||||
"resolved": "https://registry.npmjs.org/qs/-/qs-6.14.1.tgz",
|
||||
"integrity": "sha512-4EK3+xJl8Ts67nLYNwqw/dsFVnCf+qR7RgXSK9jEEm9unao3njwMDdmsdvoKBKHzxd7tCYz5e5M+SnMjdtXGQQ==",
|
||||
"version": "6.14.2",
|
||||
"resolved": "https://registry.npmjs.org/qs/-/qs-6.14.2.tgz",
|
||||
"integrity": "sha512-V/yCWTTF7VJ9hIh18Ugr2zhJMP01MY7c5kh4J870L7imm6/DIzBsNLTXzMwUA3yZ5b/KBqLx8Kp3uRvd7xSe3Q==",
|
||||
"license": "BSD-3-Clause",
|
||||
"dependencies": {
|
||||
"side-channel": "^1.1.0"
|
||||
|
|
@ -21471,9 +21476,9 @@
|
|||
}
|
||||
},
|
||||
"node_modules/terser-webpack-plugin": {
|
||||
"version": "5.3.14",
|
||||
"resolved": "https://registry.npmjs.org/terser-webpack-plugin/-/terser-webpack-plugin-5.3.14.tgz",
|
||||
"integrity": "sha512-vkZjpUjb6OMS7dhV+tILUW6BhpDR7P2L/aQSAv+Uwk+m8KATX9EccViHTJR2qDtACKPIYndLGCyl3FMo+r2LMw==",
|
||||
"version": "5.3.16",
|
||||
"resolved": "https://registry.npmjs.org/terser-webpack-plugin/-/terser-webpack-plugin-5.3.16.tgz",
|
||||
"integrity": "sha512-h9oBFCWrq78NyWWVcSwZarJkZ01c2AyGrzs1crmHZO3QUg9D61Wu4NPjBy69n7JqylFF5y+CsUZYmYEIZ3mR+Q==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@jridgewell/trace-mapping": "^0.3.25",
|
||||
|
|
@ -21928,9 +21933,9 @@
|
|||
}
|
||||
},
|
||||
"node_modules/update-browserslist-db": {
|
||||
"version": "1.1.4",
|
||||
"resolved": "https://registry.npmjs.org/update-browserslist-db/-/update-browserslist-db-1.1.4.tgz",
|
||||
"integrity": "sha512-q0SPT4xyU84saUX+tomz1WLkxUbuaJnR1xWt17M7fJtEJigJeWUNGUqrauFXsHnqev9y9JTRGwk13tFBuKby4A==",
|
||||
"version": "1.2.3",
|
||||
"resolved": "https://registry.npmjs.org/update-browserslist-db/-/update-browserslist-db-1.2.3.tgz",
|
||||
"integrity": "sha512-Js0m9cx+qOgDxo0eMiFGEueWztz+d4+M3rGlmKPT+T4IS/jP4ylw3Nwpu6cpTTP8R1MAC1kF4VbdLt3ARf209w==",
|
||||
"funding": [
|
||||
{
|
||||
"type": "opencollective",
|
||||
|
|
@ -22068,9 +22073,9 @@
|
|||
}
|
||||
},
|
||||
"node_modules/url-loader/node_modules/ajv": {
|
||||
"version": "6.12.6",
|
||||
"resolved": "https://registry.npmjs.org/ajv/-/ajv-6.12.6.tgz",
|
||||
"integrity": "sha512-j3fVLgvTo527anyYyJOGTYJbG+vnnQYvE0m5mmkc1TK+nxAppkCLMIL0aZ4dblVCNoGShhm+kzE4ZUykBoMg4g==",
|
||||
"version": "6.14.0",
|
||||
"resolved": "https://registry.npmjs.org/ajv/-/ajv-6.14.0.tgz",
|
||||
"integrity": "sha512-IWrosm/yrn43eiKqkfkHis7QioDleaXQHdDVPKg0FSwwd/DuvyX79TZnFOnYpB7dcsFAMmtFztZuXPDvSePkFw==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"fast-deep-equal": "^3.1.1",
|
||||
|
|
@ -22372,9 +22377,9 @@
|
|||
"license": "MIT"
|
||||
},
|
||||
"node_modules/watchpack": {
|
||||
"version": "2.4.4",
|
||||
"resolved": "https://registry.npmjs.org/watchpack/-/watchpack-2.4.4.tgz",
|
||||
"integrity": "sha512-c5EGNOiyxxV5qmTtAB7rbiXxi1ooX1pQKMLX/MIabJjRA0SJBQOjKF+KSVfHkr9U1cADPon0mRiVe/riyaiDUA==",
|
||||
"version": "2.5.1",
|
||||
"resolved": "https://registry.npmjs.org/watchpack/-/watchpack-2.5.1.tgz",
|
||||
"integrity": "sha512-Zn5uXdcFNIA1+1Ei5McRd+iRzfhENPCe7LeABkJtNulSxjma+l7ltNx55BWZkRlwRnpOgHqxnjyaDgJnNXnqzg==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"glob-to-regexp": "^0.4.1",
|
||||
|
|
@ -22419,9 +22424,9 @@
|
|||
"license": "BSD-2-Clause"
|
||||
},
|
||||
"node_modules/webpack": {
|
||||
"version": "5.103.0",
|
||||
"resolved": "https://registry.npmjs.org/webpack/-/webpack-5.103.0.tgz",
|
||||
"integrity": "sha512-HU1JOuV1OavsZ+mfigY0j8d1TgQgbZ6M+J75zDkpEAwYeXjWSqrGJtgnPblJjd/mAyTNQ7ygw0MiKOn6etz8yw==",
|
||||
"version": "5.105.2",
|
||||
"resolved": "https://registry.npmjs.org/webpack/-/webpack-5.105.2.tgz",
|
||||
"integrity": "sha512-dRXm0a2qcHPUBEzVk8uph0xWSjV/xZxenQQbLwnwP7caQCYpqG1qddwlyEkIDkYn0K8tvmcrZ+bOrzoQ3HxCDw==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"@types/eslint-scope": "^3.7.7",
|
||||
|
|
@ -22432,10 +22437,10 @@
|
|||
"@webassemblyjs/wasm-parser": "^1.14.1",
|
||||
"acorn": "^8.15.0",
|
||||
"acorn-import-phases": "^1.0.3",
|
||||
"browserslist": "^4.26.3",
|
||||
"browserslist": "^4.28.1",
|
||||
"chrome-trace-event": "^1.0.2",
|
||||
"enhanced-resolve": "^5.17.3",
|
||||
"es-module-lexer": "^1.2.1",
|
||||
"enhanced-resolve": "^5.19.0",
|
||||
"es-module-lexer": "^2.0.0",
|
||||
"eslint-scope": "5.1.1",
|
||||
"events": "^3.2.0",
|
||||
"glob-to-regexp": "^0.4.1",
|
||||
|
|
@ -22446,8 +22451,8 @@
|
|||
"neo-async": "^2.6.2",
|
||||
"schema-utils": "^4.3.3",
|
||||
"tapable": "^2.3.0",
|
||||
"terser-webpack-plugin": "^5.3.11",
|
||||
"watchpack": "^2.4.4",
|
||||
"terser-webpack-plugin": "^5.3.16",
|
||||
"watchpack": "^2.5.1",
|
||||
"webpack-sources": "^3.3.3"
|
||||
},
|
||||
"bin": {
|
||||
|
|
|
|||
|
|
@ -61,10 +61,26 @@
|
|||
"mermaid": ">=11.10.0",
|
||||
"gray-matter": "4.0.3",
|
||||
"glob": ">=11.1.0",
|
||||
"tar": ">=7.5.7",
|
||||
"tar": ">=7.5.8",
|
||||
"@isaacs/brace-expansion": ">=5.0.1",
|
||||
"node-forge": ">=1.3.2",
|
||||
"mdast-util-to-hast": ">=13.2.1",
|
||||
"lodash-es": ">=4.17.23"
|
||||
"lodash-es": ">=4.17.23",
|
||||
"schema-utils@3": {
|
||||
"ajv": "6.14.0"
|
||||
},
|
||||
"schema-utils@4": {
|
||||
"ajv": "8.18.0"
|
||||
},
|
||||
"file-loader": {
|
||||
"ajv": "6.14.0"
|
||||
},
|
||||
"null-loader": {
|
||||
"ajv": "6.14.0"
|
||||
},
|
||||
"url-loader": {
|
||||
"ajv": "6.14.0"
|
||||
},
|
||||
"minimatch": "10.2.1"
|
||||
}
|
||||
}
|
||||
|
|
@ -1,5 +1,5 @@
|
|||
---
|
||||
title: "[Preview] v1.81.12 - Guardrail Policy Templates & Action Builder"
|
||||
title: "v1.81.12-stable - Guardrail Policy Templates & Action Builder"
|
||||
slug: "v1-81-12"
|
||||
date: 2026-02-14T00:00:00
|
||||
authors:
|
||||
|
|
@ -27,14 +27,14 @@ import Image from '@theme/IdealImage';
|
|||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
ghcr.io/berriai/litellm:main-v1.81.12.rc.1
|
||||
ghcr.io/berriai/litellm:main-v1.81.12-stable
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="pip" label="Pip">
|
||||
|
||||
``` showLineNumbers title="pip install litellm"
|
||||
pip install litellm==1.81.12.rc1
|
||||
pip install litellm==1.81.12
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
|
|
|||
492
docs/my-website/release_notes/v1.81.14.md
Normal file
492
docs/my-website/release_notes/v1.81.14.md
Normal file
|
|
@ -0,0 +1,492 @@
|
|||
---
|
||||
title: "[Preview] v1.81.14 - New Gateway Level Guardrails & Compliance Playground"
|
||||
slug: "v1-81-14"
|
||||
date: 2026-02-21T00:00:00
|
||||
authors:
|
||||
- name: Krrish Dholakia
|
||||
title: CEO, LiteLLM
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: CTO, LiteLLM
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
## Deploy this version
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import Image from '@theme/IdealImage';
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="docker" label="Docker">
|
||||
|
||||
``` showLineNumbers title="docker run litellm"
|
||||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
ghcr.io/berriai/litellm:main-v1.81.14.rc.1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="pip" label="Pip">
|
||||
|
||||
``` showLineNumbers title="pip install litellm"
|
||||
pip install litellm==1.81.14
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Key Highlights
|
||||
|
||||
- **Guardrail Garden** — [Browse built-in and partner guardrails by use case — competitor blocking, topic filtering, GDPR, prompt injection, and more. Pick a template, customize it, attach it to a team or key.](../../docs/proxy/guardrails/policy_templates)
|
||||
- **Compliance Playground** — [Test any guardrail policy against your own traffic before it goes live. See precision, recall, and false positive rate — so you know how it'll behave in production.](../../docs/proxy/guardrails/policy_templates)
|
||||
- **3 new zero-cost built-in guardrails** — [Competitor name blocker, topic blocker, and insults filter — all gateway-level, <0.1ms latency, no external API, configurable per-team or key](../../docs/proxy/guardrails)
|
||||
- **Store Model in DB Settings via UI** - [Configure model storage directly in the Admin UI without editing config files or restarting the proxy—perfect for cloud deployments](../../docs/proxy/ui_store_model_db_setting)
|
||||
- **Claude Sonnet 4.6 — day 0** — [Full support across Anthropic and Vertex AI: reasoning, computer use, prompt caching, 200K context](../../docs/providers/anthropic)
|
||||
- **20+ performance optimizations** — Faster routing, lower logging overhead, reduced cost-calculator latency, and connection pool fixes — meaningfully less CPU and latency on every request
|
||||
|
||||
---
|
||||
|
||||
|
||||
### Guardrail Garden
|
||||
|
||||
AI Platform Admins can now browse built-in and partner guardrails from the Guardrail Garden. Guardrails are organized by use case — blocking financial advice, filtering insults, detecting competitor mentions, and more — so you can find the right one and deploy it in a few clicks.
|
||||
|
||||

|
||||
|
||||
### 3 New Built-in Guardrails
|
||||
|
||||
This release brings 3 new built-in guardrails that run directly on the gateway. This is great for AI Gateway Admins who need low latency, zero cost guardrails for their scenarios.
|
||||
|
||||
- **Denied Financial Advice** — detects requests for personalized financial advice, investment recommendations, or financial planning
|
||||
- **Denied Insults** — detects insults, name-calling, and personal attacks directed at the chatbot, staff, or other people
|
||||
- **Competitor Name Blocker** — detects mentions of competitor brands in responses
|
||||
|
||||
These guardrails are built for production and on our benchmarks had a 100% Recall and Precision.
|
||||
|
||||
### Store Model in DB Settings via UI
|
||||
|
||||
Previously, the `store_model_in_db` setting could only be configured in `proxy_config.yaml` under `general_settings`, requiring a proxy restart to take effect. Now you can enable or disable this setting directly from the Admin UI without any restarts. This is especially useful for cloud deployments where you don't have direct access to config files or want to avoid downtime. Enable `store_model_in_db` to move model definitions from your YAML into the database—reducing config complexity, improving scalability, and enabling dynamic model management across multiple proxy instances.
|
||||
|
||||

|
||||
|
||||
|
||||
#### Eval results
|
||||
|
||||
We benchmarked our new built-in guardrails against labeled datasets before shipping. You can see the results for Denied Financial Advice (207 cases) and Denied Insults (299 cases):
|
||||
|
||||
| Guardrail | Precision | Recall | F1 | Latency p50 | Cost/req |
|
||||
|-----------|-----------|--------|----|-------------|----------|
|
||||
| Denied Financial Advice | 100% | 100% | 100% | <0.1ms | $0 |
|
||||
| Denied Insults | 100% | 100% | 100% | <0.1ms | $0 |
|
||||
|
||||
100% precision means zero false positives — no legitimate messages were incorrectly blocked. 100% recall means zero false negatives — every message that should have been blocked was caught.
|
||||
|
||||
|
||||
### Compliance Playground
|
||||
|
||||
The Compliance Playground lets you test any guardrail against our pre-built eval datasets or your own custom datasets, so you can see precision, recall, and false positive rate before rolling it out to production.
|
||||
|
||||

|
||||
|
||||
|
||||
---
|
||||
|
||||
---
|
||||
|
||||
## New Providers and Endpoints
|
||||
|
||||
### New Providers (1 new provider)
|
||||
|
||||
| Provider | Supported LiteLLM Endpoints | Description |
|
||||
| -------- | --------------------------- | ----------- |
|
||||
| [IBM watsonx.ai](../../docs/providers/watsonx) | `/rerank` | Rerank support for IBM watsonx.ai models |
|
||||
|
||||
### New LLM API Endpoints (1 new endpoint)
|
||||
|
||||
| Endpoint | Method | Description | Documentation |
|
||||
| -------- | ------ | ----------- | ------------- |
|
||||
| `/v1/evals` | POST/GET | OpenAI-compatible Evals API for model evaluation | [Docs](../../docs/evals_api) |
|
||||
|
||||
---
|
||||
|
||||
## New Models / Updated Models
|
||||
|
||||
#### New Model Support (13 new models)
|
||||
|
||||
| Provider | Model | Context Window | Input ($/1M tokens) | Output ($/1M tokens) | Features |
|
||||
| -------- | ----- | -------------- | ------------------- | -------------------- | -------- |
|
||||
| Anthropic | `claude-sonnet-4-6` | 200K | $3.00 | $15.00 | Reasoning, computer use, prompt caching, vision, PDF |
|
||||
| Vertex AI | `vertex_ai/claude-opus-4-6@default` | 1M | $5.00 | $25.00 | Reasoning, computer use, prompt caching |
|
||||
| Google Gemini | `gemini/gemini-3.1-pro-preview` | 1M | $2.00 | $12.00 | Audio, video, images, PDF |
|
||||
| Google Gemini | `gemini/gemini-3.1-pro-preview-customtools` | 1M | $2.00 | $12.00 | Custom tools |
|
||||
| GitHub Copilot | `github_copilot/gpt-5.3-codex` | 128K | - | - | Responses API, function calling, vision |
|
||||
| GitHub Copilot | `github_copilot/claude-opus-4.6-fast` | 128K | - | - | Chat completions, function calling, vision |
|
||||
| Mistral | `mistral/devstral-small-latest` | 256K | $0.10 | $0.30 | Function calling, response schema |
|
||||
| Mistral | `mistral/devstral-latest` | 256K | $0.40 | $2.00 | Function calling, response schema |
|
||||
| Mistral | `mistral/devstral-medium-latest` | 256K | $0.40 | $2.00 | Function calling, response schema |
|
||||
| OpenRouter | `openrouter/minimax/minimax-m2.5` | 196K | $0.30 | $1.10 | Function calling, reasoning, prompt caching |
|
||||
| Fireworks AI | `fireworks_ai/accounts/fireworks/models/glm-4p7` | - | - | - | Chat completions |
|
||||
| Fireworks AI | `fireworks_ai/accounts/fireworks/models/minimax-m2p1` | - | - | - | Chat completions |
|
||||
| Fireworks AI | `fireworks_ai/accounts/fireworks/models/kimi-k2p5` | - | - | - | Chat completions |
|
||||
|
||||
#### Features
|
||||
|
||||
- **[Anthropic](../../docs/providers/anthropic)**
|
||||
- Day 0 support for Claude Sonnet 4.6 with reasoning, computer use, and 200K context - [PR #21401](https://github.com/BerriAI/litellm/pull/21401)
|
||||
- Add Claude Sonnet 4.6 pricing - [PR #21395](https://github.com/BerriAI/litellm/pull/21395)
|
||||
- Add day 0 feature support for Claude Sonnet 4.6 (streaming, function calling, vision) - [PR #21448](https://github.com/BerriAI/litellm/pull/21448)
|
||||
- Add `reasoning` effort and extended thinking support for Sonnet 4.6 - [PR #21598](https://github.com/BerriAI/litellm/pull/21598)
|
||||
- Fix empty system messages in `translate_system_message` - [PR #21630](https://github.com/BerriAI/litellm/pull/21630)
|
||||
- Sanitize Anthropic messages for multi-turn compatibility - [PR #21464](https://github.com/BerriAI/litellm/pull/21464)
|
||||
- Map `websearch` tool from `/v1/messages` to `/chat/completions` - [PR #21465](https://github.com/BerriAI/litellm/pull/21465)
|
||||
- Forward `reasoning` field as `reasoning_content` in delta streaming - [PR #21468](https://github.com/BerriAI/litellm/pull/21468)
|
||||
- Add server-side compaction translation from OpenAI to Anthropic format - [PR #21555](https://github.com/BerriAI/litellm/pull/21555)
|
||||
|
||||
- **[AWS Bedrock](../../docs/providers/bedrock)**
|
||||
- Native structured outputs API support (`outputConfig.textFormat`) - [PR #21222](https://github.com/BerriAI/litellm/pull/21222)
|
||||
- Support `nova/` and `nova-2/` spec prefixes for custom imported models - [PR #21359](https://github.com/BerriAI/litellm/pull/21359)
|
||||
- Broaden Nova 2 model detection to support all `nova-2-*` variants - [PR #21358](https://github.com/BerriAI/litellm/pull/21358)
|
||||
- Clamp `thinking.budget_tokens` to minimum 1024 - [PR #21306](https://github.com/BerriAI/litellm/pull/21306)
|
||||
- Fix `parallel_tool_calls` mapping for Bedrock Converse - [PR #21659](https://github.com/BerriAI/litellm/pull/21659)
|
||||
|
||||
- **[Google Gemini / Vertex AI](../../docs/providers/gemini)**
|
||||
- Day 0 support for `gemini-3.1-pro-preview` - [PR #21568](https://github.com/BerriAI/litellm/pull/21568)
|
||||
- Fix `_map_reasoning_effort_to_thinking_level` for all Gemini 3 family models - [PR #21654](https://github.com/BerriAI/litellm/pull/21654)
|
||||
- Add reasoning support via config for Gemini models - [PR #21663](https://github.com/BerriAI/litellm/pull/21663)
|
||||
|
||||
- **[Databricks](../../docs/providers/databricks)**
|
||||
- Add Databricks to supported providers for response schema - [PR #21368](https://github.com/BerriAI/litellm/pull/21368)
|
||||
- Native Responses API support for Databricks GPT models - [PR #21460](https://github.com/BerriAI/litellm/pull/21460)
|
||||
|
||||
- **[GitHub Copilot](../../docs/providers/github_copilot)**
|
||||
- Add `github_copilot/gpt-5.3-codex` and `github_copilot/claude-opus-4.6-fast` models - [PR #21316](https://github.com/BerriAI/litellm/pull/21316)
|
||||
- Fix unsupported params for ChatGPT Codex - [PR #21209](https://github.com/BerriAI/litellm/pull/21209)
|
||||
- Allow GitHub model aliases to reuse upstream model metadata - [PR #21497](https://github.com/BerriAI/litellm/pull/21497)
|
||||
|
||||
- **[Mistral](../../docs/providers/mistral)**
|
||||
- Add `devstral-2512` model aliases (`devstral-small-latest`, `devstral-latest`, `devstral-medium-latest`) - [PR #21372](https://github.com/BerriAI/litellm/pull/21372)
|
||||
|
||||
- **[IBM watsonx.ai](../../docs/providers/watsonx)**
|
||||
- Add native rerank support - [PR #21303](https://github.com/BerriAI/litellm/pull/21303)
|
||||
|
||||
- **[xAI](../../docs/providers/xai)**
|
||||
- Fix usage object in xAI responses - [PR #21559](https://github.com/BerriAI/litellm/pull/21559)
|
||||
|
||||
- **[Dashscope](../../docs/providers/dashscope)**
|
||||
- Remove list-to-str transformation that caused incorrect request formatting - [PR #21547](https://github.com/BerriAI/litellm/pull/21547)
|
||||
|
||||
- **[hosted_vllm](../../docs/providers/vllm)**
|
||||
- Convert thinking blocks to content blocks for multi-turn conversations - [PR #21557](https://github.com/BerriAI/litellm/pull/21557)
|
||||
|
||||
- **[OCI / Oracle](../../docs/providers/oci_cohere)**
|
||||
- Fix Grok output pricing - [PR #21329](https://github.com/BerriAI/litellm/pull/21329)
|
||||
|
||||
- **[AU Anthropic](../../docs/providers/anthropic)**
|
||||
- Fix `au.anthropic.claude-opus-4-6-v1` model ID - [PR #20731](https://github.com/BerriAI/litellm/pull/20731)
|
||||
|
||||
- **General**
|
||||
- Add routing based on reasoning support — skip deployments that don't support reasoning when `thinking` params are present - [PR #21302](https://github.com/BerriAI/litellm/pull/21302)
|
||||
- Add `stop` as supported param for OpenAI and Azure - [PR #21539](https://github.com/BerriAI/litellm/pull/21539)
|
||||
- Add `store` and other missing params to `OPENAI_CHAT_COMPLETION_PARAMS` - [PR #21195](https://github.com/BerriAI/litellm/pull/21195), [PR #21360](https://github.com/BerriAI/litellm/pull/21360)
|
||||
- Preserve `provider_specific_fields` from proxy responses - [PR #21220](https://github.com/BerriAI/litellm/pull/21220)
|
||||
- Add default usage data configuration - [PR #21550](https://github.com/BerriAI/litellm/pull/21550)
|
||||
|
||||
### Bug Fixes
|
||||
|
||||
- **[AWS Bedrock](../../docs/providers/bedrock)**
|
||||
- Fix service_tier cost propagation - [PR #21172](https://github.com/BerriAI/litellm/pull/21172)
|
||||
- Fix per-image pricing for multimodal embeddings - [PR #21646](https://github.com/BerriAI/litellm/pull/21646)
|
||||
- Use `batch_` prefix for Vertex AI batch IDs in `encode_file_id_with_model` - [PR #21624](https://github.com/BerriAI/litellm/pull/21624)
|
||||
|
||||
- **[Bedrock Converse](../../docs/providers/bedrock)**
|
||||
- Fix Anthropic usage object to match v1/messages spec - [PR #21295](https://github.com/BerriAI/litellm/pull/21295)
|
||||
|
||||
- **[Fireworks AI](../../docs/providers/fireworks_ai)**
|
||||
- Add missing model pricing for `glm-4p7`, `minimax-m2p1`, `kimi-k2p5` - [PR #21642](https://github.com/BerriAI/litellm/pull/21642)
|
||||
|
||||
- **[Responses API](../../docs/response_api)**
|
||||
- Fix `use None` instead of `Reasoning()` for reasoning parameter - [PR #21103](https://github.com/BerriAI/litellm/pull/21103)
|
||||
- Preserve metadata for custom callbacks on codex/responses path - [PR #21243](https://github.com/BerriAI/litellm/pull/21243)
|
||||
|
||||
---
|
||||
|
||||
## LLM API Endpoints
|
||||
|
||||
#### Features
|
||||
|
||||
- **[Responses API](../../docs/response_api)**
|
||||
- Return `finish_reason='tool_calls'` when response contains function_call items - [PR #19745](https://github.com/BerriAI/litellm/pull/19745)
|
||||
- Eliminate per-chunk thread spawning in async streaming path for significantly better throughput - [PR #21709](https://github.com/BerriAI/litellm/pull/21709)
|
||||
|
||||
- **[Evals API](../../docs/evals_api)**
|
||||
- Add support for OpenAI Evals API - [PR #21375](https://github.com/BerriAI/litellm/pull/21375)
|
||||
|
||||
- **[Batch API](../../docs/batches)**
|
||||
- Add file deletion criteria with batch references - [PR #21456](https://github.com/BerriAI/litellm/pull/21456)
|
||||
- Misc bug fixes for managed batches - [PR #21157](https://github.com/BerriAI/litellm/pull/21157)
|
||||
|
||||
- **[Pass-Through Endpoints](../../docs/pass_through/bedrock)**
|
||||
- Add method-based routing for passthrough endpoints - [PR #21543](https://github.com/BerriAI/litellm/pull/21543)
|
||||
- Preserve and forward OAuth Authorization headers through proxy layer - [PR #19912](https://github.com/BerriAI/litellm/pull/19912)
|
||||
|
||||
- **[Websearch / Tool Calling](../../docs/completion/input)**
|
||||
- Add DuckDuckGo as a search tool - [PR #21467](https://github.com/BerriAI/litellm/pull/21467)
|
||||
- Fix `pre_call_deployment_hook` not triggering via proxy router for websearch - [PR #21433](https://github.com/BerriAI/litellm/pull/21433)
|
||||
|
||||
- **General**
|
||||
- Exclude tool params for models without function calling support - [PR #21244](https://github.com/BerriAI/litellm/pull/21244)
|
||||
- Add `store` param to OpenAI chat completion params - [PR #21195](https://github.com/BerriAI/litellm/pull/21195)
|
||||
- Add reasoning support via config for per-model reasoning configuration - [PR #21663](https://github.com/BerriAI/litellm/pull/21663)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- **General**
|
||||
- Fix `api_base` resolution error for models with multiple potential endpoints - [PR #21658](https://github.com/BerriAI/litellm/pull/21658)
|
||||
- Fix session grouping broken for dict rows from `query_raw` - [PR #21435](https://github.com/BerriAI/litellm/pull/21435)
|
||||
|
||||
---
|
||||
|
||||
## Management Endpoints / UI
|
||||
|
||||
#### Features
|
||||
|
||||
- **Access Groups**
|
||||
- Add Access Group Selector to Create and Edit flow for Keys/Teams - [PR #21234](https://github.com/BerriAI/litellm/pull/21234)
|
||||
|
||||
- **Virtual Keys**
|
||||
- Fix virtual key grace period from env/UI - [PR #20321](https://github.com/BerriAI/litellm/pull/20321)
|
||||
- Fix key expiry default duration - [PR #21362](https://github.com/BerriAI/litellm/pull/21362)
|
||||
- Key Last Active Tracking — see when a key was last used - [PR #21545](https://github.com/BerriAI/litellm/pull/21545)
|
||||
- Fix `/v1/models` returning wildcard instead of expanded models for BYOK team keys - [PR #21408](https://github.com/BerriAI/litellm/pull/21408)
|
||||
- Return `failed_tokens` in delete_verification_tokens response - [PR #21609](https://github.com/BerriAI/litellm/pull/21609)
|
||||
|
||||
- **Models + Endpoints**
|
||||
- Add Model Settings Modal to Models & Endpoints page - [PR #21516](https://github.com/BerriAI/litellm/pull/21516)
|
||||
- Allow `store_model_in_db` to be set via database (not just config) - [PR #21511](https://github.com/BerriAI/litellm/pull/21511)
|
||||
- Fix `input_cost_per_token` masked/hidden in Model Info UI - [PR #21723](https://github.com/BerriAI/litellm/pull/21723)
|
||||
- Fix credentials for UI-created models in batch file uploads - [PR #21502](https://github.com/BerriAI/litellm/pull/21502)
|
||||
- Resolve credentials for UI-created models - [PR #21502](https://github.com/BerriAI/litellm/pull/21502)
|
||||
|
||||
- **Teams**
|
||||
- Allow team members to view entire team usage - [PR #21537](https://github.com/BerriAI/litellm/pull/21537)
|
||||
- Fix service account visibility for team members - [PR #21627](https://github.com/BerriAI/litellm/pull/21627)
|
||||
- Organization Info page: show member email, AntD tabs, reusable MemberTable - [PR #21745](https://github.com/BerriAI/litellm/pull/21745)
|
||||
|
||||
- **Usage / Spend Logs**
|
||||
- Allow filtering Usage by User - [PR #21351](https://github.com/BerriAI/litellm/pull/21351)
|
||||
- Inject Credential Name as Tag for Usage Page filtering - [PR #21715](https://github.com/BerriAI/litellm/pull/21715)
|
||||
- Prefix credential tags and update Tag usage banner - [PR #21739](https://github.com/BerriAI/litellm/pull/21739)
|
||||
- Show retry count for requests in Logs view - [PR #21704](https://github.com/BerriAI/litellm/pull/21704)
|
||||
- Fix Aggregated Daily Activity Endpoint performance - [PR #21613](https://github.com/BerriAI/litellm/pull/21613)
|
||||
|
||||
- **SSO / Auth**
|
||||
- Fix SSO PKCE support in multi-pod Kubernetes deployments - [PR #20314](https://github.com/BerriAI/litellm/pull/20314)
|
||||
- Preserve SSO role regardless of `role_mappings` config - [PR #21503](https://github.com/BerriAI/litellm/pull/21503)
|
||||
|
||||
- **Proxy CLI / Master Key**
|
||||
- Fix master key rotation Prisma validation errors - [PR #21330](https://github.com/BerriAI/litellm/pull/21330)
|
||||
- Handle missing `DATABASE_URL` in `append_query_params` - [PR #21239](https://github.com/BerriAI/litellm/pull/21239)
|
||||
|
||||
- **Project Management**
|
||||
- Add Project Management APIs for organizing resources - [PR #21078](https://github.com/BerriAI/litellm/pull/21078)
|
||||
|
||||
- **UI Improvements**
|
||||
- Content Filters: help edit/view categories and 1-click add with pagination - [PR #21223](https://github.com/BerriAI/litellm/pull/21223)
|
||||
- Playground: test fallbacks with UI - [PR #21007](https://github.com/BerriAI/litellm/pull/21007)
|
||||
- Add `forward_client_headers_to_llm_api` toggle to general settings - [PR #21776](https://github.com/BerriAI/litellm/pull/21776)
|
||||
- Fix `is_premium()` debug log spam on every request - [PR #20841](https://github.com/BerriAI/litellm/pull/20841)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- Spend Logs: Fix cost calculation - [PR #21152](https://github.com/BerriAI/litellm/pull/21152)
|
||||
- Logs: Fix table not updating and pagination issues - [PR #21708](https://github.com/BerriAI/litellm/pull/21708)
|
||||
- Fix `/get_image` ignoring `UI_LOGO_PATH` when `cached_logo.jpg` exists - [PR #21637](https://github.com/BerriAI/litellm/pull/21637)
|
||||
- Fix duplicate URL in `tagsSpendLogsCall` query string - [PR #20909](https://github.com/BerriAI/litellm/pull/20909)
|
||||
- Preserve `key_alias` and `team_id` metadata in `/user/daily/activity/aggregated` after key deletion or regeneration - [PR #20684](https://github.com/BerriAI/litellm/pull/20684)
|
||||
- Uncomment `response_model` in `user_info` endpoint - [PR #17430](https://github.com/BerriAI/litellm/pull/17430)
|
||||
- Allow `internal_user_viewer` to access RAG endpoints; restrict ingest to existing vector stores - [PR #21508](https://github.com/BerriAI/litellm/pull/21508)
|
||||
- Suppress warning for `litellm-dashboard` team in agent permission handler - [PR #21721](https://github.com/BerriAI/litellm/pull/21721)
|
||||
|
||||
---
|
||||
|
||||
## AI Integrations
|
||||
|
||||
### Logging
|
||||
|
||||
- **[DataDog](../../docs/proxy/logging#datadog)**
|
||||
- Add `team` tag to logs, metrics, and cost management - [PR #21449](https://github.com/BerriAI/litellm/pull/21449)
|
||||
|
||||
- **[Prometheus](../../docs/proxy/logging#prometheus)**
|
||||
- Fix double-counting of `litellm_proxy_total_requests_metric` - [PR #21159](https://github.com/BerriAI/litellm/pull/21159)
|
||||
- Guard against None metadata in Prometheus metrics - [PR #21489](https://github.com/BerriAI/litellm/pull/21489)
|
||||
- Add ASGI middleware for improved Prometheus metrics collection - [PR #20434](https://github.com/BerriAI/litellm/pull/20434)
|
||||
|
||||
- **[Langfuse](../../docs/proxy/logging#langfuse)**
|
||||
- Improve Langfuse test isolation (multiple stability fixes) - [PR #21214](https://github.com/BerriAI/litellm/pull/21214)
|
||||
|
||||
- **General**
|
||||
- Fix cost to 0 for cached responses in logging - [PR #21816](https://github.com/BerriAI/litellm/pull/21816)
|
||||
- Improve streaming proxy throughput by fixing middleware and logging bottlenecks - [PR #21501](https://github.com/BerriAI/litellm/pull/21501)
|
||||
- Reduce proxy overhead for large base64 payloads - [PR #21594](https://github.com/BerriAI/litellm/pull/21594)
|
||||
- Close streaming connections to prevent connection pool exhaustion - [PR #21213](https://github.com/BerriAI/litellm/pull/21213)
|
||||
|
||||
### Guardrails
|
||||
|
||||
- **Guardrail Garden**
|
||||
- Launch Guardrail Garden — a marketplace for pre-built guardrails deployable in one click - [PR #21732](https://github.com/BerriAI/litellm/pull/21732)
|
||||
- Redesign guardrail creation form with vertical stepper UI - [PR #21727](https://github.com/BerriAI/litellm/pull/21727)
|
||||
- Add guardrail jump link in log detail view - [PR #21437](https://github.com/BerriAI/litellm/pull/21437)
|
||||
- Guardrail tracing UI: show policy, detection method, and match details - [PR #21349](https://github.com/BerriAI/litellm/pull/21349)
|
||||
|
||||
- **AI Policy Templates**
|
||||
- Seven new ready-to-deploy policy templates ship in this release:
|
||||
- GDPR Art. 32 EU PII Protection - [PR #21340](https://github.com/BerriAI/litellm/pull/21340)
|
||||
- EU AI Act Article 5 (5 sub-guardrails, with French language support) - [PR #21342](https://github.com/BerriAI/litellm/pull/21342), [PR #21453](https://github.com/BerriAI/litellm/pull/21453), [PR #21427](https://github.com/BerriAI/litellm/pull/21427)
|
||||
- Prompt injection detection - [PR #21520](https://github.com/BerriAI/litellm/pull/21520)
|
||||
- Aviation and UAE topic filters with tag-based routing - [PR #21518](https://github.com/BerriAI/litellm/pull/21518)
|
||||
- Airline off-topic restriction - [PR #21607](https://github.com/BerriAI/litellm/pull/21607)
|
||||
- SQL injection - [PR #21806](https://github.com/BerriAI/litellm/pull/21806)
|
||||
- AI-powered policy template suggestions with latency overhead estimates - [PR #21589](https://github.com/BerriAI/litellm/pull/21589), [PR #21608](https://github.com/BerriAI/litellm/pull/21608), [PR #21620](https://github.com/BerriAI/litellm/pull/21620)
|
||||
|
||||
- **Compliance Checker**
|
||||
- Add compliance checker endpoints + UI panel - [PR #21432](https://github.com/BerriAI/litellm/pull/21432)
|
||||
- CSV dataset upload to compliance playground for batch testing - [PR #21526](https://github.com/BerriAI/litellm/pull/21526)
|
||||
|
||||
- **Built-in Guardrails**
|
||||
- Competitor name blocker: blocks by name, handles streaming, supports name variations, and splits pre/post call - [PR #21719](https://github.com/BerriAI/litellm/pull/21719), [PR #21533](https://github.com/BerriAI/litellm/pull/21533)
|
||||
- Topic blocker with both keyword and embedding-based implementations - [PR #21713](https://github.com/BerriAI/litellm/pull/21713)
|
||||
- Insults content filter - [PR #21729](https://github.com/BerriAI/litellm/pull/21729)
|
||||
- MCP Security guardrail to block unregistered MCP servers - [PR #21429](https://github.com/BerriAI/litellm/pull/21429)
|
||||
|
||||
- **[Generic Guardrails](../../docs/proxy/guardrails)**
|
||||
- Add configurable fallback to handle generic guardrail endpoint connection failures - [PR #21245](https://github.com/BerriAI/litellm/pull/21245)
|
||||
|
||||
- **[Presidio](../../docs/proxy/guardrails)**
|
||||
- Fix Presidio controls configuration - [PR #21798](https://github.com/BerriAI/litellm/pull/21798)
|
||||
|
||||
- **[LakeraAI](../../docs/proxy/guardrails)**
|
||||
- Avoid `KeyError` on missing `LAKERA_API_KEY` during initialization - [PR #21422](https://github.com/BerriAI/litellm/pull/21422)
|
||||
|
||||
### Auto Routing
|
||||
|
||||
- **Complexity-based auto routing** — new router strategy that scores requests across 7 dimensions (token count, code presence, reasoning markers, technical terms, etc.) and routes to the appropriate model tier — no embeddings or API calls required - [PR #21789](https://github.com/BerriAI/litellm/pull/21789), [Docs](../../docs/proxy/auto_routing)
|
||||
|
||||
### Prompt Management
|
||||
|
||||
- **Prompt Management API**
|
||||
- New API to interact with prompt management integrations without requiring a PR - [PR #17800](https://github.com/BerriAI/litellm/pull/17800), [PR #17946](https://github.com/BerriAI/litellm/pull/17946)
|
||||
- Fix prompt registry configuration issues - [PR #21402](https://github.com/BerriAI/litellm/pull/21402)
|
||||
|
||||
---
|
||||
|
||||
## Spend Tracking, Budgets and Rate Limiting
|
||||
|
||||
- **Fix Bedrock service_tier cost propagation** — costs from service-tier responses now correctly flow through to spend tracking - [PR #21172](https://github.com/BerriAI/litellm/pull/21172)
|
||||
- **Fix cost for cached responses** — cached responses now correctly log $0 cost instead of re-billing - [PR #21816](https://github.com/BerriAI/litellm/pull/21816)
|
||||
- **Aggregate daily activity endpoint performance** — faster queries for `/user/daily/activity/aggregated` - [PR #21613](https://github.com/BerriAI/litellm/pull/21613)
|
||||
- **Preserve key_alias and team_id metadata** in `/user/daily/activity/aggregated` after key deletion or regeneration - [PR #20684](https://github.com/BerriAI/litellm/pull/20684)
|
||||
- **Inject Credential Name as Tag** for granular usage page filtering by credential - [PR #21715](https://github.com/BerriAI/litellm/pull/21715)
|
||||
|
||||
---
|
||||
|
||||
## MCP Gateway
|
||||
|
||||
- **OpenAPI-to-MCP** — Convert any OpenAPI spec to an MCP server via API or UI - [PR #21575](https://github.com/BerriAI/litellm/pull/21575), [PR #21662](https://github.com/BerriAI/litellm/pull/21662)
|
||||
- **MCP User Permissions** — Fine-grained permissions for end users on MCP servers - [PR #21462](https://github.com/BerriAI/litellm/pull/21462)
|
||||
- **MCP Security Guardrail** — Block calls to unregistered MCP servers - [PR #21429](https://github.com/BerriAI/litellm/pull/21429)
|
||||
- **Fix StreamableHTTPSessionManager** — Revert to stateless mode to prevent session state issues - [PR #21323](https://github.com/BerriAI/litellm/pull/21323)
|
||||
- **Fix Bedrock AgentCore Accept header** — Add required Accept header for AgentCore MCP server requests - [PR #21551](https://github.com/BerriAI/litellm/pull/21551)
|
||||
|
||||
---
|
||||
|
||||
## Performance / Loadbalancing / Reliability improvements
|
||||
|
||||
**Logging & callback overhead**
|
||||
|
||||
- Move async/sync callback separation from per-request to callback registration time — ~30% speedup for callback-heavy deployments - [PR #20354](https://github.com/BerriAI/litellm/pull/20354)
|
||||
- Skip Pydantic Usage round-trip in logging payload — reduces serialization overhead per request - [PR #21003](https://github.com/BerriAI/litellm/pull/21003)
|
||||
- Skip duplicate `get_standard_logging_object_payload` calls for non-streaming requests - [PR #20440](https://github.com/BerriAI/litellm/pull/20440)
|
||||
- Reuse `LiteLLM_Params` object across the request lifecycle - [PR #20593](https://github.com/BerriAI/litellm/pull/20593)
|
||||
- Optimize `add_litellm_data_to_request` hot path - [PR #20526](https://github.com/BerriAI/litellm/pull/20526)
|
||||
- Optimize `model_dump_with_preserved_fields` - [PR #20882](https://github.com/BerriAI/litellm/pull/20882)
|
||||
- Pre-compute OpenAI client init params at module load instead of per-request - [PR #20789](https://github.com/BerriAI/litellm/pull/20789)
|
||||
- Reduce proxy overhead for large base64 payloads - [PR #21594](https://github.com/BerriAI/litellm/pull/21594)
|
||||
- Improve streaming proxy throughput by fixing middleware and logging bottlenecks - [PR #21501](https://github.com/BerriAI/litellm/pull/21501)
|
||||
- Eliminate per-chunk thread spawning in Responses API async streaming - [PR #21709](https://github.com/BerriAI/litellm/pull/21709)
|
||||
|
||||
**Cost calculation**
|
||||
|
||||
- Optimize `completion_cost()` with early-exit and caching - [PR #20448](https://github.com/BerriAI/litellm/pull/20448)
|
||||
- Cost calculator: reduce repeated lookups and dict copies - [PR #20541](https://github.com/BerriAI/litellm/pull/20541)
|
||||
|
||||
**Router & load balancing**
|
||||
|
||||
- Remove quadratic deployment scan in usage-based routing v2 - [PR #21211](https://github.com/BerriAI/litellm/pull/21211)
|
||||
- Avoid O(n²) membership scans in team deployment filter - [PR #21210](https://github.com/BerriAI/litellm/pull/21210)
|
||||
- Avoid O(n) alias scan for non-alias `get_model_list` lookups - [PR #21136](https://github.com/BerriAI/litellm/pull/21136)
|
||||
- Increase default LRU cache size to reduce multi-model cache thrash - [PR #21139](https://github.com/BerriAI/litellm/pull/21139)
|
||||
- Cache `get_model_access_groups()` no-args result on Router - [PR #20374](https://github.com/BerriAI/litellm/pull/20374)
|
||||
- Deployment affinity routing callback — route to the same deployment for a session - [PR #19143](https://github.com/BerriAI/litellm/pull/19143)
|
||||
- Session-ID-based routing — use `session_id` for consistent routing within a session - [PR #21763](https://github.com/BerriAI/litellm/pull/21763)
|
||||
|
||||
**Connection management & reliability**
|
||||
|
||||
- Fix Redis connection pool reliability — prevent connection exhaustion under load - [PR #21717](https://github.com/BerriAI/litellm/pull/21717)
|
||||
- Fix Prisma connection self-heal for auth and runtime reconnection (reverted, will be re-introduced with fixes) - [PR #21706](https://github.com/BerriAI/litellm/pull/21706)
|
||||
- Make `PodLockManager.release_lock` atomic compare-and-delete - [PR #21226](https://github.com/BerriAI/litellm/pull/21226)
|
||||
|
||||
---
|
||||
|
||||
## Database Changes
|
||||
|
||||
### Schema Updates
|
||||
|
||||
| Table | Change Type | Description | PR |
|
||||
| ----- | ----------- | ----------- | -- |
|
||||
| `LiteLLM_DeletedVerificationToken` | New Column | Added `project_id` column | [PR #21587](https://github.com/BerriAI/litellm/pull/21587) |
|
||||
| `LiteLLM_ProjectTable` | New Table | Project management for organizing resources | [PR #21078](https://github.com/BerriAI/litellm/pull/21078) |
|
||||
| `LiteLLM_VerificationToken` | New Column | Added `last_active` timestamp for key activity tracking | [PR #21545](https://github.com/BerriAI/litellm/pull/21545) |
|
||||
| `LiteLLM_ManagedVectorStoreTable` | Migration | Make vector store migration idempotent | [PR #21325](https://github.com/BerriAI/litellm/pull/21325) |
|
||||
|
||||
---
|
||||
|
||||
## Documentation Updates
|
||||
|
||||
- Add OpenAI Agents SDK with LiteLLM guide - [PR #21311](https://github.com/BerriAI/litellm/pull/21311)
|
||||
- Access Groups documentation - [PR #21236](https://github.com/BerriAI/litellm/pull/21236)
|
||||
- Anthropic beta headers documentation - [PR #21320](https://github.com/BerriAI/litellm/pull/21320)
|
||||
- Latency overhead troubleshooting guide - [PR #21600](https://github.com/BerriAI/litellm/pull/21600), [PR #21603](https://github.com/BerriAI/litellm/pull/21603)
|
||||
- Add rollback safety check guide - [PR #21743](https://github.com/BerriAI/litellm/pull/21743)
|
||||
- Incident report: vLLM Embeddings broken by encoding_format parameter - [PR #21474](https://github.com/BerriAI/litellm/pull/21474)
|
||||
- Incident report: Claude Code beta headers - [PR #21485](https://github.com/BerriAI/litellm/pull/21485)
|
||||
- Mark v1.81.12 as stable - [PR #21809](https://github.com/BerriAI/litellm/pull/21809)
|
||||
|
||||
---
|
||||
|
||||
## New Contributors
|
||||
|
||||
* @mjkam made their first contribution in [PR #21306](https://github.com/BerriAI/litellm/pull/21306)
|
||||
* @saneroen made their first contribution in [PR #21243](https://github.com/BerriAI/litellm/pull/21243)
|
||||
* @vincentkoc made their first contribution in [PR #21239](https://github.com/BerriAI/litellm/pull/21239)
|
||||
* @felixti made their first contribution in [PR #19745](https://github.com/BerriAI/litellm/pull/19745)
|
||||
* @anttttti made their first contribution in [PR #20731](https://github.com/BerriAI/litellm/pull/20731)
|
||||
* @ndgigliotti made their first contribution in [PR #21222](https://github.com/BerriAI/litellm/pull/21222)
|
||||
* @iamadamreed made their first contribution in [PR #19912](https://github.com/BerriAI/litellm/pull/19912)
|
||||
* @sahukanishka made their first contribution in [PR #21220](https://github.com/BerriAI/litellm/pull/21220)
|
||||
* @namabile made their first contribution in [PR #21195](https://github.com/BerriAI/litellm/pull/21195)
|
||||
* @stronk7 made their first contribution in [PR #21372](https://github.com/BerriAI/litellm/pull/21372)
|
||||
* @ZeroAurora made their first contribution in [PR #21547](https://github.com/BerriAI/litellm/pull/21547)
|
||||
* @SolitudePy made their first contribution in [PR #21497](https://github.com/BerriAI/litellm/pull/21497)
|
||||
* @SherifWaly made their first contribution in [PR #21557](https://github.com/BerriAI/litellm/pull/21557)
|
||||
* @dkindlund made their first contribution in [PR #21633](https://github.com/BerriAI/litellm/pull/21633)
|
||||
* @cagojeiger made their first contribution in [PR #21664](https://github.com/BerriAI/litellm/pull/21664)
|
||||
|
||||
---
|
||||
|
||||
## Full Changelog
|
||||
[v1.81.12.rc.1...v1.81.14.rc.1](https://github.com/BerriAI/litellm/compare/v1.81.12.rc.1...v1.81.14.rc.1)
|
||||
|
|
@ -161,6 +161,7 @@ const sidebars = {
|
|||
]
|
||||
},
|
||||
"tutorials/opencode_integration",
|
||||
"tutorials/openclaw_integration",
|
||||
"tutorials/cost_tracking_coding",
|
||||
"tutorials/cursor_integration",
|
||||
"tutorials/github_copilot_integration",
|
||||
|
|
@ -334,6 +335,7 @@ const sidebars = {
|
|||
"proxy/ui_credentials",
|
||||
"proxy/ai_hub",
|
||||
"proxy/model_compare_ui",
|
||||
"proxy/ui_store_model_db_setting",
|
||||
]
|
||||
},
|
||||
{
|
||||
|
|
|
|||
9
license_cache.json
Normal file
9
license_cache.json
Normal file
|
|
@ -0,0 +1,9 @@
|
|||
{
|
||||
"tornado:6.5.3": "Apache-2.0",
|
||||
"redisvl:0.4.1": "MIT",
|
||||
"google-cloud-iam:2.19.1": "Apache 2.0",
|
||||
"google-genai:1.37.0": "Apache-2.0",
|
||||
"azure-keyvault:4.2.0": "MIT License",
|
||||
"soundfile:0.12.1": "BSD 3-Clause License",
|
||||
"openapi-core:0.21.0": "BSD-3-Clause"
|
||||
}
|
||||
|
|
@ -0,0 +1,5 @@
|
|||
-- Ensure project_id column exists in LiteLLM_VerificationToken.
|
||||
-- The original migration (20251113000000_add_project_table) adds this column,
|
||||
-- but if it failed partway through (e.g. LiteLLM_ProjectTable already existed)
|
||||
-- and was resolved as idempotent, the ALTER TABLE step may have been skipped.
|
||||
ALTER TABLE "LiteLLM_VerificationToken" ADD COLUMN IF NOT EXISTS "project_id" TEXT;
|
||||
|
|
@ -0,0 +1,17 @@
|
|||
-- DropIndex
|
||||
DROP INDEX "LiteLLM_PolicyTable_policy_name_key";
|
||||
|
||||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_PolicyTable" ADD COLUMN "is_latest" BOOLEAN NOT NULL DEFAULT true,
|
||||
ADD COLUMN "parent_version_id" TEXT,
|
||||
ADD COLUMN "production_at" TIMESTAMP(3),
|
||||
ADD COLUMN "published_at" TIMESTAMP(3),
|
||||
ADD COLUMN "version_number" INTEGER NOT NULL DEFAULT 1,
|
||||
ADD COLUMN "version_status" TEXT NOT NULL DEFAULT 'production';
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_PolicyTable_policy_name_version_status_idx" ON "LiteLLM_PolicyTable"("policy_name", "version_status");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE UNIQUE INDEX "LiteLLM_PolicyTable_policy_name_version_number_key" ON "LiteLLM_PolicyTable"("policy_name", "version_number");
|
||||
|
||||
|
|
@ -213,53 +213,6 @@ model LiteLLM_DeletedTeamTable {
|
|||
@@index([created_at])
|
||||
}
|
||||
|
||||
// Audit table for deleted teams - preserves spend and team information for historical tracking
|
||||
model LiteLLM_DeletedTeamTable {
|
||||
id String @id @default(uuid())
|
||||
team_id String // Original team_id
|
||||
team_alias String?
|
||||
organization_id String?
|
||||
object_permission_id String?
|
||||
admins String[]
|
||||
members String[]
|
||||
members_with_roles Json @default("{}")
|
||||
metadata Json @default("{}")
|
||||
max_budget Float?
|
||||
soft_budget Float?
|
||||
spend Float @default(0.0)
|
||||
models String[]
|
||||
max_parallel_requests Int?
|
||||
tpm_limit BigInt?
|
||||
rpm_limit BigInt?
|
||||
budget_duration String?
|
||||
budget_reset_at DateTime?
|
||||
blocked Boolean @default(false)
|
||||
model_spend Json @default("{}")
|
||||
model_max_budget Json @default("{}")
|
||||
router_settings Json? @default("{}")
|
||||
team_member_permissions String[] @default([])
|
||||
access_group_ids String[] @default([])
|
||||
policies String[] @default([])
|
||||
model_id Int? // id for LiteLLM_ModelTable -> stores team-level model aliases
|
||||
allow_team_guardrail_config Boolean @default(false)
|
||||
|
||||
// Original timestamps from team creation/updates
|
||||
created_at DateTime? @map("created_at")
|
||||
updated_at DateTime? @map("updated_at")
|
||||
|
||||
// Deletion metadata
|
||||
deleted_at DateTime @default(now()) @map("deleted_at")
|
||||
deleted_by String? @map("deleted_by") // User who deleted the team
|
||||
deleted_by_api_key String? @map("deleted_by_api_key") // API key hash that performed the deletion
|
||||
litellm_changed_by String? @map("litellm_changed_by") // From litellm-changed-by header if provided
|
||||
|
||||
@@index([team_id])
|
||||
@@index([deleted_at])
|
||||
@@index([organization_id])
|
||||
@@index([team_alias])
|
||||
@@index([created_at])
|
||||
}
|
||||
|
||||
// Track spend, rate limit, budget Users
|
||||
model LiteLLM_UserTable {
|
||||
user_id String @id
|
||||
|
|
@ -320,6 +273,7 @@ model LiteLLM_MCPServerTable {
|
|||
alias String?
|
||||
description String?
|
||||
url String?
|
||||
spec_path String?
|
||||
transport String @default("sse")
|
||||
auth_type String?
|
||||
credentials Json? @default("{}")
|
||||
|
|
@ -1009,20 +963,29 @@ model LiteLLM_SkillsTable {
|
|||
updated_by String?
|
||||
}
|
||||
|
||||
// Policy table for storing guardrail policies
|
||||
// Policy table for storing guardrail policies (versioned)
|
||||
model LiteLLM_PolicyTable {
|
||||
policy_id String @id @default(uuid())
|
||||
policy_name String @unique
|
||||
inherit String? // Name of parent policy to inherit from
|
||||
description String?
|
||||
guardrails_add String[] @default([])
|
||||
guardrails_remove String[] @default([])
|
||||
condition Json? @default("{}") // Policy conditions (e.g., model matching)
|
||||
pipeline Json? // Optional guardrail pipeline (mode + steps[])
|
||||
created_at DateTime @default(now())
|
||||
created_by String?
|
||||
updated_at DateTime @default(now()) @updatedAt
|
||||
updated_by String?
|
||||
policy_id String @id @default(uuid())
|
||||
policy_name String // No longer @unique; use @@unique([policy_name, version_number])
|
||||
version_number Int @default(1)
|
||||
version_status String @default("production") // "draft" | "published" | "production"
|
||||
parent_version_id String?
|
||||
is_latest Boolean @default(true)
|
||||
published_at DateTime?
|
||||
production_at DateTime?
|
||||
inherit String? // Name of parent policy to inherit from
|
||||
description String?
|
||||
guardrails_add String[] @default([])
|
||||
guardrails_remove String[] @default([])
|
||||
condition Json? @default("{}") // Policy conditions (e.g., model matching)
|
||||
pipeline Json? // Optional guardrail pipeline (mode + steps[])
|
||||
created_at DateTime @default(now())
|
||||
created_by String?
|
||||
updated_at DateTime @default(now()) @updatedAt
|
||||
updated_by String?
|
||||
|
||||
@@unique([policy_name, version_number])
|
||||
@@index([policy_name, version_status])
|
||||
}
|
||||
|
||||
// Policy attachment table for defining where policies apply
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "litellm-proxy-extras"
|
||||
version = "0.4.45"
|
||||
version = "0.4.46"
|
||||
description = "Additional files for the LiteLLM Proxy. Reduces the size of the main litellm package."
|
||||
authors = ["BerriAI"]
|
||||
readme = "README.md"
|
||||
|
|
@ -22,7 +22,7 @@ requires = ["poetry-core"]
|
|||
build-backend = "poetry.core.masonry.api"
|
||||
|
||||
[tool.commitizen]
|
||||
version = "0.4.45"
|
||||
version = "0.4.46"
|
||||
version_files = [
|
||||
"pyproject.toml:version",
|
||||
"../requirements.txt:litellm-proxy-extras==",
|
||||
|
|
|
|||
|
|
@ -98,6 +98,7 @@ _custom_logger_compatible_callbacks_literal = Literal[
|
|||
"openmeter",
|
||||
"logfire",
|
||||
"literalai",
|
||||
"litellm_agent",
|
||||
"dynamic_rate_limiter",
|
||||
"dynamic_rate_limiter_v3",
|
||||
"langsmith",
|
||||
|
|
|
|||
|
|
@ -127,7 +127,7 @@
|
|||
"compact-2026-01-12": null,
|
||||
"computer-use-2025-01-24": "computer-use-2025-01-24",
|
||||
"computer-use-2025-11-24": "computer-use-2025-11-24",
|
||||
"context-1m-2025-08-07": null,
|
||||
"context-1m-2025-08-07": "context-1m-2025-08-07",
|
||||
"context-management-2025-06-27": "context-management-2025-06-27",
|
||||
"effort-2025-11-24": null,
|
||||
"fast-mode-2026-02-01": null,
|
||||
|
|
@ -179,4 +179,4 @@
|
|||
"web-fetch-2025-09-10": "web-fetch-2025-09-10",
|
||||
"web-search-2025-03-05": "web-search-2025-03-05"
|
||||
}
|
||||
}
|
||||
}
|
||||
|
|
|
|||
|
|
@ -119,6 +119,42 @@ if TYPE_CHECKING:
|
|||
else:
|
||||
LitellmLoggingObject = Any
|
||||
|
||||
# Pre-resolved CallTypes enum values for fast membership checks
|
||||
_A2A_CALL_TYPES = frozenset({
|
||||
CallTypes.asend_message.value,
|
||||
CallTypes.send_message.value,
|
||||
})
|
||||
|
||||
_VIDEO_CALL_TYPES = frozenset({
|
||||
CallTypes.create_video.value,
|
||||
CallTypes.acreate_video.value,
|
||||
CallTypes.video_remix.value,
|
||||
CallTypes.avideo_remix.value,
|
||||
})
|
||||
|
||||
_SPEECH_CALL_TYPES = frozenset({
|
||||
CallTypes.speech.value,
|
||||
CallTypes.aspeech.value,
|
||||
})
|
||||
|
||||
_TRANSCRIPTION_CALL_TYPES = frozenset({
|
||||
CallTypes.atranscription.value,
|
||||
CallTypes.transcription.value,
|
||||
})
|
||||
|
||||
_RERANK_CALL_TYPES = frozenset({
|
||||
CallTypes.rerank.value,
|
||||
CallTypes.arerank.value,
|
||||
})
|
||||
|
||||
_SEARCH_CALL_TYPES = frozenset({
|
||||
CallTypes.search.value,
|
||||
CallTypes.asearch.value,
|
||||
})
|
||||
|
||||
_AREALTIME_CALL_TYPE = CallTypes.arealtime.value
|
||||
_MCP_CALL_TYPE = CallTypes.call_mcp_tool.value
|
||||
|
||||
|
||||
def _cost_per_token_custom_pricing_helper(
|
||||
prompt_tokens: float = 0,
|
||||
|
|
@ -1121,10 +1157,7 @@ def completion_cost( # noqa: PLR0915
|
|||
completion_tokens = token_counter(model=model, text=completion)
|
||||
|
||||
# Handle A2A calls before model check - A2A doesn't require a model
|
||||
if call_type in (
|
||||
CallTypes.asend_message.value,
|
||||
CallTypes.send_message.value,
|
||||
):
|
||||
if call_type in _A2A_CALL_TYPES:
|
||||
from litellm.a2a_protocol.cost_calculator import A2ACostCalculator
|
||||
|
||||
return A2ACostCalculator.calculate_a2a_cost(
|
||||
|
|
@ -1160,12 +1193,7 @@ def completion_cost( # noqa: PLR0915
|
|||
optional_params=optional_params,
|
||||
call_type=call_type,
|
||||
)
|
||||
elif (
|
||||
call_type == CallTypes.create_video.value
|
||||
or call_type == CallTypes.acreate_video.value
|
||||
or call_type == CallTypes.video_remix.value
|
||||
or call_type == CallTypes.avideo_remix.value
|
||||
):
|
||||
elif call_type in _VIDEO_CALL_TYPES:
|
||||
### VIDEO GENERATION COST CALCULATION ###
|
||||
usage_obj = getattr(completion_response, "usage", None)
|
||||
if completion_response is not None and usage_obj:
|
||||
|
|
@ -1194,22 +1222,13 @@ def completion_cost( # noqa: PLR0915
|
|||
duration_seconds=0.0, # Default to 0 if no duration available
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
)
|
||||
elif (
|
||||
call_type == CallTypes.speech.value
|
||||
or call_type == CallTypes.aspeech.value
|
||||
):
|
||||
elif call_type in _SPEECH_CALL_TYPES:
|
||||
prompt_characters = litellm.utils._count_characters(text=prompt)
|
||||
elif (
|
||||
call_type == CallTypes.atranscription.value
|
||||
or call_type == CallTypes.transcription.value
|
||||
):
|
||||
elif call_type in _TRANSCRIPTION_CALL_TYPES:
|
||||
audio_transcription_file_duration = getattr(
|
||||
completion_response, "duration", 0.0
|
||||
)
|
||||
elif (
|
||||
call_type == CallTypes.rerank.value
|
||||
or call_type == CallTypes.arerank.value
|
||||
):
|
||||
elif call_type in _RERANK_CALL_TYPES:
|
||||
if completion_response is not None and isinstance(
|
||||
completion_response, RerankResponse
|
||||
):
|
||||
|
|
@ -1228,10 +1247,7 @@ def completion_cost( # noqa: PLR0915
|
|||
billed_units.get("search_units") or 1
|
||||
) # cohere charges per request by default.
|
||||
completion_tokens = search_units
|
||||
elif (
|
||||
call_type == CallTypes.search.value
|
||||
or call_type == CallTypes.asearch.value
|
||||
):
|
||||
elif call_type in _SEARCH_CALL_TYPES:
|
||||
from litellm.search import search_provider_cost_per_query
|
||||
|
||||
# Extract number_of_queries from optional_params or default to 1
|
||||
|
|
@ -1300,7 +1316,7 @@ def completion_cost( # noqa: PLR0915
|
|||
)
|
||||
|
||||
return _final_cost
|
||||
elif call_type == CallTypes.arealtime.value and isinstance(
|
||||
elif call_type == _AREALTIME_CALL_TYPE and isinstance(
|
||||
completion_response, LiteLLMRealtimeStreamLoggingObject
|
||||
):
|
||||
if (
|
||||
|
|
@ -1319,7 +1335,7 @@ def completion_cost( # noqa: PLR0915
|
|||
custom_llm_provider=custom_llm_provider,
|
||||
litellm_model_name=model,
|
||||
)
|
||||
elif call_type == CallTypes.call_mcp_tool.value:
|
||||
elif call_type == _MCP_CALL_TYPE:
|
||||
from litellm.proxy._experimental.mcp_server.cost_calculator import (
|
||||
MCPCostCalculator,
|
||||
)
|
||||
|
|
@ -1393,7 +1409,7 @@ def completion_cost( # noqa: PLR0915
|
|||
cache_creation_input_tokens=cache_creation_input_tokens,
|
||||
cache_read_input_tokens=cache_read_input_tokens,
|
||||
usage_object=cost_per_token_usage_object,
|
||||
call_type=cast(CallTypesLiteral, call_type),
|
||||
call_type=call_type,
|
||||
audio_transcription_file_duration=audio_transcription_file_duration,
|
||||
rerank_billed_units=rerank_billed_units,
|
||||
service_tier=service_tier,
|
||||
|
|
@ -1401,12 +1417,17 @@ def completion_cost( # noqa: PLR0915
|
|||
)
|
||||
|
||||
# Get additional costs from provider (e.g., routing fees, infrastructure costs)
|
||||
additional_costs = _get_additional_costs(
|
||||
model=model,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
prompt_tokens=prompt_tokens,
|
||||
completion_tokens=completion_tokens,
|
||||
)
|
||||
# Only azure_ai implements additional costs
|
||||
if custom_llm_provider == "azure_ai":
|
||||
additional_costs = _get_additional_costs(
|
||||
model=model,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
prompt_tokens=prompt_tokens,
|
||||
completion_tokens=completion_tokens,
|
||||
)
|
||||
else:
|
||||
additional_costs = None
|
||||
|
||||
|
||||
_final_cost = (
|
||||
prompt_tokens_cost_usd_dollar + completion_tokens_cost_usd_dollar
|
||||
|
|
|
|||
5
litellm/integrations/litellm_agent/__init__.py
Normal file
5
litellm/integrations/litellm_agent/__init__.py
Normal file
|
|
@ -0,0 +1,5 @@
|
|||
"""LiteLLM Agent integration - model name resolver for litellm_agent/ prefix."""
|
||||
|
||||
from .litellm_agent_model_resolver import LiteLLMAgentModelResolver
|
||||
|
||||
__all__ = ["LiteLLMAgentModelResolver"]
|
||||
|
|
@ -0,0 +1,79 @@
|
|||
"""
|
||||
Hook for LiteLLM that strips the litellm_agent/ prefix from model names.
|
||||
|
||||
When model is litellm_agent/gpt-3.5-turbo, this hook replaces it with gpt-3.5-turbo
|
||||
before the completion call, similar to langfuse/model resolution.
|
||||
"""
|
||||
|
||||
from typing import Dict, List, Optional, Tuple
|
||||
|
||||
from litellm.integrations.custom_logger import CustomLogger
|
||||
from litellm.types.llms.openai import AllMessageValues
|
||||
from litellm.types.prompts.init_prompts import PromptSpec
|
||||
from litellm.types.utils import StandardCallbackDynamicParams
|
||||
|
||||
LITELLM_AGENT_PREFIX = "litellm_agent/"
|
||||
|
||||
|
||||
class LiteLLMAgentModelResolver(CustomLogger):
|
||||
"""
|
||||
CustomLogger that strips litellm_agent/ prefix from model names.
|
||||
|
||||
Enables model configs like litellm_agent/gpt-3.5-turbo to resolve to gpt-3.5-turbo.
|
||||
"""
|
||||
|
||||
def get_chat_completion_prompt(
|
||||
self,
|
||||
model: str,
|
||||
messages: List[AllMessageValues],
|
||||
non_default_params: dict,
|
||||
prompt_id: Optional[str],
|
||||
prompt_variables: Optional[dict],
|
||||
dynamic_callback_params: StandardCallbackDynamicParams,
|
||||
prompt_spec: Optional[PromptSpec] = None,
|
||||
prompt_label: Optional[str] = None,
|
||||
prompt_version: Optional[int] = None,
|
||||
ignore_prompt_manager_model: Optional[bool] = False,
|
||||
ignore_prompt_manager_optional_params: Optional[bool] = False,
|
||||
) -> Tuple[str, List[AllMessageValues], dict]:
|
||||
"""
|
||||
Strip litellm_agent/ prefix from model name.
|
||||
|
||||
Returns:
|
||||
(resolved_model, messages, non_default_params)
|
||||
"""
|
||||
if ignore_prompt_manager_model:
|
||||
return model, messages, non_default_params
|
||||
resolved_model = model.replace(LITELLM_AGENT_PREFIX, "", 1)
|
||||
return resolved_model, messages, non_default_params
|
||||
|
||||
async def async_get_chat_completion_prompt(
|
||||
self,
|
||||
model: str,
|
||||
messages: List[AllMessageValues],
|
||||
non_default_params: dict,
|
||||
prompt_id: Optional[str],
|
||||
prompt_variables: Optional[dict],
|
||||
dynamic_callback_params: StandardCallbackDynamicParams,
|
||||
litellm_logging_obj: object,
|
||||
prompt_spec: Optional[PromptSpec] = None,
|
||||
tools: Optional[List[Dict]] = None,
|
||||
prompt_label: Optional[str] = None,
|
||||
prompt_version: Optional[int] = None,
|
||||
ignore_prompt_manager_model: Optional[bool] = False,
|
||||
ignore_prompt_manager_optional_params: Optional[bool] = False,
|
||||
) -> Tuple[str, List[AllMessageValues], dict]:
|
||||
"""Async delegate to get_chat_completion_prompt."""
|
||||
return self.get_chat_completion_prompt(
|
||||
model=model,
|
||||
messages=messages,
|
||||
non_default_params=non_default_params,
|
||||
prompt_id=prompt_id,
|
||||
prompt_variables=prompt_variables,
|
||||
dynamic_callback_params=dynamic_callback_params,
|
||||
prompt_spec=prompt_spec,
|
||||
prompt_label=prompt_label,
|
||||
prompt_version=prompt_version,
|
||||
ignore_prompt_manager_model=ignore_prompt_manager_model,
|
||||
ignore_prompt_manager_optional_params=ignore_prompt_manager_optional_params,
|
||||
)
|
||||
|
|
@ -18,11 +18,11 @@ from litellm.integrations.azure_storage.azure_storage import AzureBlobStorageLog
|
|||
from litellm.integrations.bitbucket import BitBucketPromptManager
|
||||
from litellm.integrations.braintrust_logging import BraintrustLogger
|
||||
from litellm.integrations.cloudzero.cloudzero import CloudZeroLogger
|
||||
from litellm.integrations.focus.focus_logger import FocusLogger
|
||||
from litellm.integrations.datadog.datadog import DataDogLogger
|
||||
from litellm.integrations.datadog.datadog_llm_obs import DataDogLLMObsLogger
|
||||
from litellm.integrations.deepeval import DeepEvalLogger
|
||||
from litellm.integrations.dotprompt import DotpromptManager
|
||||
from litellm.integrations.focus.focus_logger import FocusLogger
|
||||
from litellm.integrations.galileo import GalileoObserve
|
||||
from litellm.integrations.gcs_bucket.gcs_bucket import GCSBucketLogger
|
||||
from litellm.integrations.gcs_pubsub.pub_sub import GcsPubSubLogger
|
||||
|
|
@ -33,6 +33,7 @@ from litellm.integrations.langfuse.langfuse_prompt_management import (
|
|||
LangfusePromptManagement,
|
||||
)
|
||||
from litellm.integrations.langsmith import LangsmithLogger
|
||||
from litellm.integrations.litellm_agent import LiteLLMAgentModelResolver
|
||||
from litellm.integrations.literal_ai import LiteralAILogger
|
||||
from litellm.integrations.mlflow import MlflowLogger
|
||||
from litellm.integrations.openmeter import OpenMeterLogger
|
||||
|
|
@ -61,6 +62,7 @@ class CustomLoggerRegistry:
|
|||
"galileo": GalileoObserve,
|
||||
"langsmith": LangsmithLogger,
|
||||
"literalai": LiteralAILogger,
|
||||
"litellm_agent": LiteLLMAgentModelResolver,
|
||||
"prometheus": PrometheusLogger,
|
||||
"datadog": DataDogLogger,
|
||||
"datadog_llm_observability": DataDogLLMObsLogger,
|
||||
|
|
|
|||
|
|
@ -147,6 +147,7 @@ from ..integrations.langfuse.langfuse import LangFuseLogger
|
|||
from ..integrations.langfuse.langfuse_handler import LangFuseHandler
|
||||
from ..integrations.langfuse.langfuse_prompt_management import LangfusePromptManagement
|
||||
from ..integrations.langsmith import LangsmithLogger
|
||||
from ..integrations.litellm_agent import LiteLLMAgentModelResolver
|
||||
from ..integrations.literal_ai import LiteralAILogger
|
||||
from ..integrations.logfire_logger import LogfireLevel, LogfireLogger
|
||||
from ..integrations.lunary import LunaryLogger
|
||||
|
|
@ -587,6 +588,11 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
if prompt_id:
|
||||
return True
|
||||
|
||||
# Check if model uses litellm_agent prefix (model replacement without prompt_id)
|
||||
model = non_default_params.get("model", "")
|
||||
if isinstance(model, str) and model.startswith("litellm_agent/"):
|
||||
return True
|
||||
|
||||
if self._should_run_prompt_management_hooks_without_prompt_id(
|
||||
non_default_params=non_default_params,
|
||||
tools=tools,
|
||||
|
|
@ -1394,6 +1400,12 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
used for consistent cost calculation across response headers + logging integrations.
|
||||
"""
|
||||
|
||||
if cache_hit is None:
|
||||
cache_hit = self.model_call_details.get("cache_hit", False)
|
||||
|
||||
if cache_hit is True:
|
||||
return 0.0
|
||||
|
||||
if isinstance(result, BaseModel) and hasattr(result, "_hidden_params"):
|
||||
hidden_params = getattr(result, "_hidden_params", {})
|
||||
if (
|
||||
|
|
@ -1626,8 +1638,14 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
self.model_call_details["litellm_params"]["metadata"] = {}
|
||||
self.model_call_details["litellm_params"]["metadata"]["hidden_params"] = getattr(logging_result, "_hidden_params", {}) # type: ignore
|
||||
|
||||
if "response_cost" in hidden_params:
|
||||
if self.model_call_details.get("cache_hit") is True:
|
||||
self.model_call_details["response_cost"] = 0.0
|
||||
elif "response_cost" in hidden_params:
|
||||
self.model_call_details["response_cost"] = hidden_params["response_cost"]
|
||||
elif self.model_call_details.get("response_cost") is not None:
|
||||
# Preserve response_cost if already calculated (e.g., by pass-through
|
||||
# handlers like Gemini/Vertex which call completion_cost directly)
|
||||
pass
|
||||
else:
|
||||
self.model_call_details["response_cost"] = self._response_cost_calculator(
|
||||
result=logging_result
|
||||
|
|
@ -1639,6 +1657,13 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
logging_result, start_time, end_time
|
||||
)
|
||||
|
||||
if (
|
||||
standard_logging_payload := self.model_call_details.get(
|
||||
"standard_logging_object"
|
||||
)
|
||||
) is not None:
|
||||
emit_standard_logging_payload(standard_logging_payload)
|
||||
|
||||
def _build_standard_logging_payload(
|
||||
self, init_response_obj: Any, start_time: Any, end_time: Any
|
||||
) -> Any:
|
||||
|
|
@ -1752,6 +1777,12 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
] = self._build_standard_logging_payload(
|
||||
result, start_time, end_time
|
||||
)
|
||||
if (
|
||||
standard_logging_payload := self.model_call_details.get(
|
||||
"standard_logging_object"
|
||||
)
|
||||
) is not None:
|
||||
emit_standard_logging_payload(standard_logging_payload)
|
||||
elif standard_logging_object is not None:
|
||||
self.model_call_details[
|
||||
"standard_logging_object"
|
||||
|
|
@ -1949,7 +1980,24 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
)
|
||||
## LOGGING HOOK ##
|
||||
for callback in callbacks:
|
||||
if isinstance(callback, CustomLogger):
|
||||
if isinstance(callback, CustomGuardrail):
|
||||
from litellm.types.guardrails import GuardrailEventHooks
|
||||
|
||||
if (
|
||||
callback.should_run_guardrail(
|
||||
data=self.model_call_details,
|
||||
event_type=GuardrailEventHooks.logging_only,
|
||||
)
|
||||
is not True
|
||||
):
|
||||
continue
|
||||
|
||||
self.model_call_details, result = callback.logging_hook(
|
||||
kwargs=self.model_call_details,
|
||||
result=result,
|
||||
call_type=self.call_type,
|
||||
)
|
||||
elif isinstance(callback, CustomLogger):
|
||||
self.model_call_details, result = callback.logging_hook(
|
||||
kwargs=self.model_call_details,
|
||||
result=result,
|
||||
|
|
@ -2458,23 +2506,29 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
|
||||
self.model_call_details["async_complete_streaming_response"] = result
|
||||
|
||||
# cost calculation not possible for pass-through
|
||||
self.model_call_details["response_cost"] = None
|
||||
# Only set response_cost to None if not already calculated by
|
||||
# pass-through handlers (e.g. Gemini/Vertex handlers already
|
||||
# compute cost via completion_cost)
|
||||
if self.model_call_details.get("response_cost") is None:
|
||||
self.model_call_details["response_cost"] = None
|
||||
|
||||
## STANDARDIZED LOGGING PAYLOAD
|
||||
self.model_call_details[
|
||||
"standard_logging_object"
|
||||
] = self._build_standard_logging_payload(
|
||||
result, start_time, end_time
|
||||
)
|
||||
|
||||
# print standard logging payload
|
||||
if (
|
||||
standard_logging_payload := self.model_call_details.get(
|
||||
# Only build standard_logging_object if not already built by
|
||||
# _success_handler_helper_fn
|
||||
if self.model_call_details.get("standard_logging_object") is None:
|
||||
## STANDARDIZED LOGGING PAYLOAD
|
||||
self.model_call_details[
|
||||
"standard_logging_object"
|
||||
] = self._build_standard_logging_payload(
|
||||
result, start_time, end_time
|
||||
)
|
||||
) is not None:
|
||||
emit_standard_logging_payload(standard_logging_payload)
|
||||
|
||||
# print standard logging payload
|
||||
if (
|
||||
standard_logging_payload := self.model_call_details.get(
|
||||
"standard_logging_object"
|
||||
)
|
||||
) is not None:
|
||||
emit_standard_logging_payload(standard_logging_payload)
|
||||
callbacks = self.get_combined_callback_list(
|
||||
dynamic_success_callbacks=self.dynamic_async_success_callbacks,
|
||||
global_callbacks=litellm._async_success_callback,
|
||||
|
|
@ -3211,6 +3265,8 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
is_async: bool,
|
||||
streaming_chunks: List[Any],
|
||||
) -> Optional[Union[ModelResponse, TextCompletionResponse, ResponsesAPIResponse]]:
|
||||
if self.stream is not True:
|
||||
return None
|
||||
if isinstance(result, ModelResponse):
|
||||
return result
|
||||
elif isinstance(result, TextCompletionResponse):
|
||||
|
|
@ -3579,6 +3635,14 @@ def _init_custom_logger_compatible_class( # noqa: PLR0915
|
|||
_literalai_logger = LiteralAILogger()
|
||||
_in_memory_loggers.append(_literalai_logger)
|
||||
return _literalai_logger # type: ignore
|
||||
elif logging_integration == "litellm_agent":
|
||||
for callback in _in_memory_loggers:
|
||||
if isinstance(callback, LiteLLMAgentModelResolver):
|
||||
return callback # type: ignore
|
||||
|
||||
_litellm_agent_resolver = LiteLLMAgentModelResolver()
|
||||
_in_memory_loggers.append(_litellm_agent_resolver)
|
||||
return _litellm_agent_resolver # type: ignore
|
||||
elif logging_integration == "prometheus":
|
||||
PrometheusLogger = _get_cached_prometheus_logger()
|
||||
|
||||
|
|
@ -4133,6 +4197,10 @@ def get_custom_logger_compatible_class( # noqa: PLR0915
|
|||
for callback in _in_memory_loggers:
|
||||
if isinstance(callback, LiteralAILogger):
|
||||
return callback
|
||||
elif logging_integration == "litellm_agent":
|
||||
for callback in _in_memory_loggers:
|
||||
if isinstance(callback, LiteLLMAgentModelResolver):
|
||||
return callback
|
||||
elif logging_integration == "prometheus":
|
||||
PrometheusLogger = _get_cached_prometheus_logger()
|
||||
for callback in _in_memory_loggers:
|
||||
|
|
@ -4604,6 +4672,37 @@ class StandardLoggingPayloadSetup:
|
|||
|
||||
raise ValueError(f"usage is required, got={usage} of type {type(usage)}")
|
||||
|
||||
@staticmethod
|
||||
def get_usage_as_dict(
|
||||
response_obj: Optional[dict],
|
||||
combined_usage_object: Optional[Usage] = None,
|
||||
) -> dict:
|
||||
"""
|
||||
Like get_usage_from_response_obj but returns a plain dict, skipping
|
||||
the Pydantic Usage construction on the hot path.
|
||||
"""
|
||||
_empty: dict = {"prompt_tokens": 0, "completion_tokens": 0, "total_tokens": 0}
|
||||
if combined_usage_object is not None:
|
||||
return combined_usage_object.model_dump()
|
||||
if not response_obj:
|
||||
return _empty
|
||||
_raw = response_obj.get("usage", None)
|
||||
if _raw is None:
|
||||
return _empty
|
||||
if isinstance(_raw, ResponseAPIUsage):
|
||||
return ResponseAPILoggingUtils._transform_response_api_usage_to_chat_usage(
|
||||
_raw
|
||||
).model_dump()
|
||||
if isinstance(_raw, dict):
|
||||
if ResponseAPILoggingUtils._is_response_api_usage(_raw):
|
||||
return ResponseAPILoggingUtils._transform_response_api_usage_to_chat_usage(
|
||||
_raw
|
||||
).model_dump()
|
||||
return _raw
|
||||
if isinstance(_raw, Usage):
|
||||
return _raw.model_dump()
|
||||
return _empty
|
||||
|
||||
@staticmethod
|
||||
def get_model_cost_information(
|
||||
base_model: Optional[str],
|
||||
|
|
@ -5060,7 +5159,8 @@ def get_standard_logging_object_payload(
|
|||
completion_start_time = kwargs.get("completion_start_time", end_time)
|
||||
call_type = kwargs.get("call_type")
|
||||
cache_hit = kwargs.get("cache_hit", False)
|
||||
usage = StandardLoggingPayloadSetup.get_usage_from_response_obj(
|
||||
# Extract usage as a plain dict, avoiding Pydantic round-trip
|
||||
usage_dict = StandardLoggingPayloadSetup.get_usage_as_dict(
|
||||
response_obj=response_obj,
|
||||
combined_usage_object=cast(
|
||||
Optional[Usage], kwargs.get("combined_usage_object")
|
||||
|
|
@ -5107,7 +5207,7 @@ def get_standard_logging_object_payload(
|
|||
vector_store_request_metadata=kwargs.get(
|
||||
"vector_store_request_metadata", None
|
||||
),
|
||||
usage_object=usage.model_dump(),
|
||||
usage_object=usage_dict,
|
||||
proxy_server_request=proxy_server_request,
|
||||
start_time=start_time,
|
||||
response_id=id,
|
||||
|
|
@ -5193,9 +5293,9 @@ def get_standard_logging_object_payload(
|
|||
cache_key=clean_hidden_params["cache_key"],
|
||||
response_cost=response_cost,
|
||||
cost_breakdown=logging_obj.cost_breakdown,
|
||||
total_tokens=usage.total_tokens,
|
||||
prompt_tokens=usage.prompt_tokens,
|
||||
completion_tokens=usage.completion_tokens,
|
||||
total_tokens=usage_dict.get("total_tokens", 0),
|
||||
prompt_tokens=usage_dict.get("prompt_tokens", 0),
|
||||
completion_tokens=usage_dict.get("completion_tokens", 0),
|
||||
request_tags=request_tags,
|
||||
end_user=end_user_id or "",
|
||||
api_base=StandardLoggingPayloadSetup.strip_trailing_slash(
|
||||
|
|
@ -5439,3 +5539,4 @@ def create_dummy_standard_logging_payload() -> StandardLoggingPayload:
|
|||
model_parameters={"stream": True},
|
||||
hidden_params=hidden_params,
|
||||
)
|
||||
|
||||
|
|
|
|||
|
|
@ -16,6 +16,15 @@ from litellm.types.utils import (
|
|||
)
|
||||
from litellm.utils import get_model_info
|
||||
|
||||
# Pre-resolved CallTypes enum values for fast membership checks
|
||||
_IMAGE_RESPONSE_CALL_TYPES = frozenset({
|
||||
CallTypes.image_generation.value,
|
||||
CallTypes.aimage_generation.value,
|
||||
PassthroughCallTypes.passthrough_image_generation.value,
|
||||
CallTypes.image_edit.value,
|
||||
CallTypes.aimage_edit.value,
|
||||
})
|
||||
|
||||
|
||||
def _is_above_128k(tokens: float) -> bool:
|
||||
if tokens > 128000:
|
||||
|
|
@ -189,9 +198,25 @@ def _get_token_base_cost(
|
|||
cache_read_cost = cast(float, _get_cost_per_unit(model_info, cache_read_cost_key))
|
||||
|
||||
## CHECK IF ABOVE THRESHOLD
|
||||
# Optimization: collect threshold keys first to avoid sorting all model_info keys.
|
||||
# Most models don't have threshold pricing, so we can return early.
|
||||
threshold_keys = [
|
||||
k for k in model_info if k.startswith("input_cost_per_token_above_")
|
||||
]
|
||||
if not threshold_keys:
|
||||
return (
|
||||
prompt_base_cost,
|
||||
completion_base_cost,
|
||||
cache_creation_cost,
|
||||
cache_creation_cost_above_1hr,
|
||||
cache_read_cost,
|
||||
)
|
||||
|
||||
# Only sort the threshold keys (typically 1-2 keys instead of 66+)
|
||||
threshold: Optional[float] = None
|
||||
for key, value in sorted(model_info.items(), reverse=True):
|
||||
if key.startswith("input_cost_per_token_above_") and value is not None:
|
||||
for key in sorted(threshold_keys, reverse=True):
|
||||
value = model_info.get(key)
|
||||
if value is not None:
|
||||
try:
|
||||
# Handle both formats: _above_128k_tokens and _above_128_tokens
|
||||
threshold_str = key.split("_above_")[1].split("_tokens")[0]
|
||||
|
|
@ -502,47 +527,52 @@ def _calculate_input_cost(
|
|||
prompt_cost += float(prompt_tokens_details["cache_hit_tokens"]) * cache_read_cost
|
||||
|
||||
### AUDIO COST
|
||||
prompt_cost += calculate_cost_component(
|
||||
model_info, "input_cost_per_audio_token", prompt_tokens_details["audio_tokens"]
|
||||
)
|
||||
if prompt_tokens_details["audio_tokens"]:
|
||||
prompt_cost += calculate_cost_component(
|
||||
model_info, "input_cost_per_audio_token", prompt_tokens_details["audio_tokens"]
|
||||
)
|
||||
|
||||
### IMAGE TOKEN COST
|
||||
# For image token costs:
|
||||
# First check if input_cost_per_image_token is available. If not, default to generic input_cost_per_token.
|
||||
image_token_cost_key = "input_cost_per_image_token"
|
||||
if model_info.get(image_token_cost_key) is None:
|
||||
image_token_cost_key = "input_cost_per_token"
|
||||
prompt_cost += calculate_cost_component(
|
||||
model_info, image_token_cost_key, prompt_tokens_details["image_tokens"]
|
||||
)
|
||||
if prompt_tokens_details["image_tokens"]:
|
||||
# For image token costs:
|
||||
# First check if input_cost_per_image_token is available. If not, default to generic input_cost_per_token.
|
||||
image_token_cost_key = "input_cost_per_image_token"
|
||||
if model_info.get(image_token_cost_key) is None:
|
||||
image_token_cost_key = "input_cost_per_token"
|
||||
prompt_cost += calculate_cost_component(
|
||||
model_info, image_token_cost_key, prompt_tokens_details["image_tokens"]
|
||||
)
|
||||
|
||||
### CACHE WRITING COST - Now uses tiered pricing
|
||||
prompt_cost += calculate_cache_writing_cost(
|
||||
cache_creation_tokens=prompt_tokens_details["cache_creation_tokens"],
|
||||
cache_creation_token_details=prompt_tokens_details[
|
||||
"cache_creation_token_details"
|
||||
],
|
||||
cache_creation_cost_above_1hr=cache_creation_cost_above_1hr,
|
||||
cache_creation_cost=cache_creation_cost,
|
||||
)
|
||||
if prompt_tokens_details["cache_creation_tokens"] or prompt_tokens_details["cache_creation_token_details"] is not None:
|
||||
prompt_cost += calculate_cache_writing_cost(
|
||||
cache_creation_tokens=prompt_tokens_details["cache_creation_tokens"],
|
||||
cache_creation_token_details=prompt_tokens_details[
|
||||
"cache_creation_token_details"
|
||||
],
|
||||
cache_creation_cost_above_1hr=cache_creation_cost_above_1hr,
|
||||
cache_creation_cost=cache_creation_cost,
|
||||
)
|
||||
|
||||
### CHARACTER COST
|
||||
|
||||
prompt_cost += calculate_cost_component(
|
||||
model_info, "input_cost_per_character", prompt_tokens_details["character_count"]
|
||||
)
|
||||
if prompt_tokens_details["character_count"]:
|
||||
prompt_cost += calculate_cost_component(
|
||||
model_info, "input_cost_per_character", prompt_tokens_details["character_count"]
|
||||
)
|
||||
|
||||
### IMAGE COUNT COST
|
||||
prompt_cost += calculate_cost_component(
|
||||
model_info, "input_cost_per_image", prompt_tokens_details["image_count"]
|
||||
)
|
||||
if prompt_tokens_details["image_count"]:
|
||||
prompt_cost += calculate_cost_component(
|
||||
model_info, "input_cost_per_image", prompt_tokens_details["image_count"]
|
||||
)
|
||||
|
||||
### VIDEO LENGTH COST
|
||||
prompt_cost += calculate_cost_component(
|
||||
model_info,
|
||||
"input_cost_per_video_per_second",
|
||||
prompt_tokens_details["video_length_seconds"],
|
||||
)
|
||||
if prompt_tokens_details["video_length_seconds"]:
|
||||
prompt_cost += calculate_cost_component(
|
||||
model_info,
|
||||
"input_cost_per_video_per_second",
|
||||
prompt_tokens_details["video_length_seconds"],
|
||||
)
|
||||
|
||||
return prompt_cost
|
||||
|
||||
|
|
@ -667,18 +697,11 @@ def generic_cost_per_token( # noqa: PLR0915
|
|||
## TEXT COST
|
||||
completion_cost = float(text_tokens) * completion_base_cost
|
||||
|
||||
_output_cost_per_audio_token = _get_cost_per_unit(
|
||||
model_info, "output_cost_per_audio_token", None
|
||||
)
|
||||
_output_cost_per_reasoning_token = _get_cost_per_unit(
|
||||
model_info, "output_cost_per_reasoning_token", None
|
||||
)
|
||||
_output_cost_per_image_token = _get_cost_per_unit(
|
||||
model_info, "output_cost_per_image_token", None
|
||||
)
|
||||
|
||||
## AUDIO COST
|
||||
if not is_text_tokens_total and audio_tokens is not None and audio_tokens > 0:
|
||||
_output_cost_per_audio_token = _get_cost_per_unit(
|
||||
model_info, "output_cost_per_audio_token", None
|
||||
)
|
||||
_output_cost_per_audio_token = (
|
||||
_output_cost_per_audio_token
|
||||
if _output_cost_per_audio_token is not None
|
||||
|
|
@ -688,6 +711,9 @@ def generic_cost_per_token( # noqa: PLR0915
|
|||
|
||||
## REASONING COST
|
||||
if not is_text_tokens_total and reasoning_tokens and reasoning_tokens > 0:
|
||||
_output_cost_per_reasoning_token = _get_cost_per_unit(
|
||||
model_info, "output_cost_per_reasoning_token", None
|
||||
)
|
||||
_output_cost_per_reasoning_token = (
|
||||
_output_cost_per_reasoning_token
|
||||
if _output_cost_per_reasoning_token is not None
|
||||
|
|
@ -697,6 +723,9 @@ def generic_cost_per_token( # noqa: PLR0915
|
|||
|
||||
## IMAGE COST
|
||||
if not is_text_tokens_total and image_tokens and image_tokens > 0:
|
||||
_output_cost_per_image_token = _get_cost_per_unit(
|
||||
model_info, "output_cost_per_image_token", None
|
||||
)
|
||||
_output_cost_per_image_token = (
|
||||
_output_cost_per_image_token
|
||||
if _output_cost_per_image_token is not None
|
||||
|
|
@ -718,18 +747,7 @@ class CostCalculatorUtils:
|
|||
- Image Edit
|
||||
- Passthrough Image Generation
|
||||
"""
|
||||
if call_type in [
|
||||
# image generation
|
||||
CallTypes.image_generation.value,
|
||||
CallTypes.aimage_generation.value,
|
||||
# passthrough image generation
|
||||
PassthroughCallTypes.passthrough_image_generation.value,
|
||||
# image edit
|
||||
CallTypes.image_edit.value,
|
||||
CallTypes.aimage_edit.value,
|
||||
]:
|
||||
return True
|
||||
return False
|
||||
return call_type in _IMAGE_RESPONSE_CALL_TYPES
|
||||
|
||||
@staticmethod
|
||||
def route_image_generation_cost_calculator(
|
||||
|
|
|
|||
|
|
@ -6,7 +6,6 @@ from typing import Dict, Iterable, List, Literal, Optional, Tuple, Union
|
|||
|
||||
import litellm
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm._uuid import uuid
|
||||
from litellm.constants import RESPONSE_FORMAT_TOOL_NAME
|
||||
from litellm.litellm_core_utils.prompt_templates.common_utils import (
|
||||
_extract_reasoning_content,
|
||||
|
|
@ -46,6 +45,12 @@ from litellm.types.utils import (
|
|||
|
||||
from .get_headers import get_response_headers
|
||||
|
||||
_MESSAGE_FIELDS: frozenset = frozenset(Message.model_fields.keys())
|
||||
_CHOICES_FIELDS: frozenset = frozenset(Choices.model_fields.keys())
|
||||
_MODEL_RESPONSE_FIELDS: frozenset = frozenset(ModelResponse.model_fields.keys()) | {
|
||||
"usage"
|
||||
}
|
||||
|
||||
|
||||
def _safe_convert_created_field(created_value) -> int:
|
||||
"""
|
||||
|
|
@ -443,7 +448,6 @@ def convert_to_model_response_object( # noqa: PLR0915
|
|||
bool
|
||||
] = None, # used for supporting 'json_schema' on older models
|
||||
):
|
||||
received_args = locals()
|
||||
additional_headers = get_response_headers(_response_headers)
|
||||
|
||||
if hidden_params is None:
|
||||
|
|
@ -551,10 +555,8 @@ def convert_to_model_response_object( # noqa: PLR0915
|
|||
provider_specific_fields = dict(
|
||||
choice["message"].get("provider_specific_fields", None) or {}
|
||||
)
|
||||
message_keys = Message.model_fields.keys()
|
||||
for field in choice["message"].keys():
|
||||
if field not in message_keys:
|
||||
provider_specific_fields[field] = choice["message"][field]
|
||||
for f in choice["message"].keys() - _MESSAGE_FIELDS:
|
||||
provider_specific_fields[f] = choice["message"][f]
|
||||
|
||||
# Handle reasoning models that display `reasoning_content` within `content`
|
||||
reasoning_content, content = _extract_reasoning_content(
|
||||
|
|
@ -603,10 +605,9 @@ def convert_to_model_response_object( # noqa: PLR0915
|
|||
finish_reason = "tool_calls"
|
||||
|
||||
## PROVIDER SPECIFIC FIELDS ##
|
||||
provider_specific_fields = {}
|
||||
for field in choice.keys():
|
||||
if field not in Choices.model_fields.keys():
|
||||
provider_specific_fields[field] = choice[field]
|
||||
provider_specific_fields = {
|
||||
f: choice[f] for f in choice.keys() - _CHOICES_FIELDS
|
||||
}
|
||||
|
||||
logprobs = choice.get("logprobs", None)
|
||||
enhancements = choice.get("enhancements", None)
|
||||
|
|
@ -630,7 +631,9 @@ def convert_to_model_response_object( # noqa: PLR0915
|
|||
)
|
||||
|
||||
if "id" in response_object:
|
||||
model_response_object.id = response_object["id"] or str(uuid.uuid4())
|
||||
# Preserve the auto-generated id from ModelResponse.__init__
|
||||
# when the provider returns a falsy id (None, "")
|
||||
model_response_object.id = response_object["id"] or model_response_object.id
|
||||
|
||||
if "system_fingerprint" in response_object:
|
||||
model_response_object.system_fingerprint = response_object[
|
||||
|
|
@ -665,10 +668,8 @@ def convert_to_model_response_object( # noqa: PLR0915
|
|||
if _response_headers is not None:
|
||||
model_response_object._response_headers = _response_headers
|
||||
|
||||
special_keys = list(litellm.ModelResponse.model_fields.keys())
|
||||
special_keys.append("usage")
|
||||
for k, v in response_object.items():
|
||||
if k not in special_keys:
|
||||
if k not in _MODEL_RESPONSE_FIELDS:
|
||||
setattr(model_response_object, k, v)
|
||||
|
||||
return model_response_object
|
||||
|
|
@ -785,6 +786,17 @@ def convert_to_model_response_object( # noqa: PLR0915
|
|||
|
||||
return model_response_object
|
||||
except Exception:
|
||||
received_args = dict(
|
||||
response_object=response_object,
|
||||
model_response_object=model_response_object,
|
||||
response_type=response_type,
|
||||
stream=stream,
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
hidden_params=hidden_params,
|
||||
_response_headers=_response_headers,
|
||||
convert_tool_call_to_json_mode=convert_tool_call_to_json_mode,
|
||||
)
|
||||
raise Exception(
|
||||
f"Invalid response object {traceback.format_exc()}\n\nreceived_args={received_args}"
|
||||
)
|
||||
|
|
|
|||
|
|
@ -25,13 +25,31 @@ class LoggingCallbackManager:
|
|||
- Keep a reasonable MAX_CALLBACKS limit (this ensures callbacks don't exponentially grow and consume CPU Resources)
|
||||
"""
|
||||
|
||||
def add_litellm_input_callback(self, callback: Union[CustomLogger, str]):
|
||||
# healthy maximum number of callbacks - unlikely someone needs more than 20
|
||||
MAX_CALLBACKS = 30
|
||||
|
||||
def _is_async_callable(self, callback) -> bool:
|
||||
"""Check if a callback is async. Used to auto-route callbacks to the correct list."""
|
||||
try:
|
||||
from litellm.litellm_core_utils.coroutine_checker import coroutine_checker
|
||||
|
||||
return coroutine_checker.is_async_callable(callback)
|
||||
except Exception:
|
||||
return False
|
||||
|
||||
def add_litellm_input_callback(self, callback: Union[CustomLogger, str, Callable]):
|
||||
"""
|
||||
Add a input callback to litellm.input_callback
|
||||
Add a input callback to litellm.input_callback.
|
||||
Auto-routes async callbacks to litellm._async_input_callback.
|
||||
"""
|
||||
self._safe_add_callback_to_list(
|
||||
callback=callback, parent_list=litellm.input_callback
|
||||
)
|
||||
if not isinstance(callback, str) and self._is_async_callable(callback):
|
||||
self._safe_add_callback_to_list(
|
||||
callback=callback, parent_list=litellm._async_input_callback
|
||||
)
|
||||
else:
|
||||
self._safe_add_callback_to_list(
|
||||
callback=callback, parent_list=litellm.input_callback
|
||||
)
|
||||
|
||||
def add_litellm_service_callback(
|
||||
self, callback: Union[CustomLogger, str, Callable]
|
||||
|
|
@ -57,21 +75,38 @@ class LoggingCallbackManager:
|
|||
self, callback: Union[CustomLogger, str, Callable]
|
||||
):
|
||||
"""
|
||||
Add a success callback to `litellm.success_callback`
|
||||
Add a success callback to `litellm.success_callback`.
|
||||
Auto-routes async callbacks to litellm._async_success_callback.
|
||||
Special-cases 'dynamodb' and 'openmeter' as async callbacks.
|
||||
"""
|
||||
self._safe_add_callback_to_list(
|
||||
callback=callback, parent_list=litellm.success_callback
|
||||
)
|
||||
if isinstance(callback, str) and callback in ("dynamodb", "openmeter"):
|
||||
self._safe_add_callback_to_list(
|
||||
callback=callback, parent_list=litellm._async_success_callback
|
||||
)
|
||||
elif not isinstance(callback, str) and self._is_async_callable(callback):
|
||||
self._safe_add_callback_to_list(
|
||||
callback=callback, parent_list=litellm._async_success_callback
|
||||
)
|
||||
else:
|
||||
self._safe_add_callback_to_list(
|
||||
callback=callback, parent_list=litellm.success_callback
|
||||
)
|
||||
|
||||
def add_litellm_failure_callback(
|
||||
self, callback: Union[CustomLogger, str, Callable]
|
||||
):
|
||||
"""
|
||||
Add a failure callback to `litellm.failure_callback`
|
||||
Add a failure callback to `litellm.failure_callback`.
|
||||
Auto-routes async callbacks to litellm._async_failure_callback.
|
||||
"""
|
||||
self._safe_add_callback_to_list(
|
||||
callback=callback, parent_list=litellm.failure_callback
|
||||
)
|
||||
if not isinstance(callback, str) and self._is_async_callable(callback):
|
||||
self._safe_add_callback_to_list(
|
||||
callback=callback, parent_list=litellm._async_failure_callback
|
||||
)
|
||||
else:
|
||||
self._safe_add_callback_to_list(
|
||||
callback=callback, parent_list=litellm.failure_callback
|
||||
)
|
||||
|
||||
def add_litellm_async_success_callback(
|
||||
self, callback: Union[CustomLogger, Callable, str]
|
||||
|
|
|
|||
|
|
@ -452,7 +452,7 @@ def update_responses_input_with_model_file_ids(
|
|||
|
||||
For managed files (unified file IDs), uses model_file_id_mapping if provided,
|
||||
otherwise decodes the base64-encoded unified file ID and extracts the llm_output_file_id directly.
|
||||
|
||||
|
||||
Args:
|
||||
input: The responses API input parameter
|
||||
model_id: The model ID to use for looking up provider-specific file IDs
|
||||
|
|
@ -488,9 +488,13 @@ def update_responses_input_with_model_file_ids(
|
|||
file_id = content_item.get("file_id")
|
||||
if file_id:
|
||||
provider_file_id = file_id # Default to original
|
||||
|
||||
|
||||
# Check if we have a mapping for this file ID
|
||||
if model_file_id_mapping and model_id and file_id in model_file_id_mapping:
|
||||
if (
|
||||
model_file_id_mapping
|
||||
and model_id
|
||||
and file_id in model_file_id_mapping
|
||||
):
|
||||
# Use the model-specific file ID from mapping
|
||||
provider_file_id = (
|
||||
model_file_id_mapping.get(file_id, {}).get(model_id)
|
||||
|
|
@ -501,15 +505,19 @@ def update_responses_input_with_model_file_ids(
|
|||
updated_content.append(updated_content_item)
|
||||
else:
|
||||
# Check if this is a base64-encoded unified file ID without mapping
|
||||
is_unified_file_id = _is_base64_encoded_unified_file_id(file_id)
|
||||
is_unified_file_id = _is_base64_encoded_unified_file_id(
|
||||
file_id
|
||||
)
|
||||
if is_unified_file_id:
|
||||
# Fallback: decode unified file ID
|
||||
unified_file_id = convert_b64_uid_to_unified_uid(file_id)
|
||||
unified_file_id = convert_b64_uid_to_unified_uid(
|
||||
file_id
|
||||
)
|
||||
if "llm_output_file_id," in unified_file_id:
|
||||
provider_file_id = unified_file_id.split(
|
||||
"llm_output_file_id,"
|
||||
)[1].split(";")[0]
|
||||
|
||||
|
||||
updated_content_item = content_item.copy()
|
||||
updated_content_item["file_id"] = provider_file_id
|
||||
updated_content.append(updated_content_item)
|
||||
|
|
@ -534,9 +542,9 @@ def update_responses_tools_with_model_file_ids(
|
|||
) -> Optional[List[Dict[str, Any]]]:
|
||||
"""
|
||||
Updates responses API tools with provider-specific file IDs.
|
||||
|
||||
|
||||
Handles code_interpreter tools with container.file_ids.
|
||||
|
||||
|
||||
Args:
|
||||
tools: The responses API tools parameter
|
||||
model_id: The model ID to use for looking up provider-specific file IDs
|
||||
|
|
@ -545,18 +553,18 @@ def update_responses_tools_with_model_file_ids(
|
|||
"""
|
||||
if not tools or not isinstance(tools, list):
|
||||
return tools
|
||||
|
||||
|
||||
if not model_file_id_mapping or not model_id:
|
||||
return tools
|
||||
|
||||
|
||||
updated_tools = []
|
||||
for tool in tools:
|
||||
if not isinstance(tool, dict):
|
||||
updated_tools.append(tool)
|
||||
continue
|
||||
|
||||
|
||||
updated_tool = tool.copy()
|
||||
|
||||
|
||||
# Handle code_interpreter with container file_ids
|
||||
if tool.get("type") == "code_interpreter":
|
||||
container = tool.get("container")
|
||||
|
|
@ -578,14 +586,14 @@ def update_responses_tools_with_model_file_ids(
|
|||
updated_file_ids.append(file_id)
|
||||
else:
|
||||
updated_file_ids.append(file_id)
|
||||
|
||||
|
||||
# Update the tool with new file IDs
|
||||
updated_container = container.copy()
|
||||
updated_container["file_ids"] = updated_file_ids
|
||||
updated_tool["container"] = updated_container
|
||||
|
||||
|
||||
updated_tools.append(updated_tool)
|
||||
|
||||
|
||||
return updated_tools
|
||||
|
||||
|
||||
|
|
@ -1104,6 +1112,46 @@ def set_last_user_message(
|
|||
return messages
|
||||
|
||||
|
||||
def add_system_prompt_to_messages(
|
||||
messages: List[AllMessageValues],
|
||||
system_prompt: str,
|
||||
merge_with_first_system: bool = False,
|
||||
) -> List[AllMessageValues]:
|
||||
"""
|
||||
Add a system prompt to the messages list.
|
||||
|
||||
Args:
|
||||
messages: List of chat completion messages
|
||||
system_prompt: The system prompt content to add. If empty or None, returns messages unchanged.
|
||||
merge_with_first_system: If True and the first message is already a system message,
|
||||
prepends the new prompt to that message's content. If False, adds a new system
|
||||
message at the beginning.
|
||||
|
||||
Returns:
|
||||
New list of messages with the system prompt added
|
||||
"""
|
||||
if not system_prompt:
|
||||
return list(messages)
|
||||
|
||||
if merge_with_first_system and messages and messages[0].get("role") == "system":
|
||||
first = dict(messages[0])
|
||||
existing_content = first.get("content", "")
|
||||
merged_content: Union[str, List[Dict[str, str]]]
|
||||
if isinstance(existing_content, str):
|
||||
merged_content = f"{system_prompt.strip()}\n\n{existing_content}"
|
||||
elif isinstance(existing_content, list):
|
||||
merged_content = [{"type": "text", "text": system_prompt.strip()}] + list(
|
||||
existing_content
|
||||
)
|
||||
else:
|
||||
merged_content = [{"type": "text", "text": system_prompt.strip()}]
|
||||
first["content"] = merged_content
|
||||
return [cast(AllMessageValues, first)] + list(messages[1:])
|
||||
|
||||
system_message: AllMessageValues = {"role": "system", "content": system_prompt}
|
||||
return [system_message, *messages]
|
||||
|
||||
|
||||
def convert_prefix_message_to_non_prefix_messages(
|
||||
messages: List[AllMessageValues],
|
||||
) -> List[AllMessageValues]:
|
||||
|
|
|
|||
|
|
@ -8,6 +8,7 @@ import time
|
|||
import traceback
|
||||
from typing import Any, Callable, Dict, List, Optional, Union, cast
|
||||
|
||||
import anyio
|
||||
import httpx
|
||||
from pydantic import BaseModel
|
||||
|
||||
|
|
@ -156,6 +157,27 @@ class CustomStreamWrapper:
|
|||
def __aiter__(self):
|
||||
return self
|
||||
|
||||
async def aclose(self):
|
||||
if self.completion_stream is not None:
|
||||
stream_to_close = self.completion_stream
|
||||
self.completion_stream = None
|
||||
# Shield from anyio cancellation so cleanup awaits can complete.
|
||||
# Without this, CancelledError is thrown into every await during
|
||||
# task group cancellation, preventing HTTP connection release.
|
||||
with anyio.CancelScope(shield=True):
|
||||
try:
|
||||
if hasattr(stream_to_close, "aclose"):
|
||||
await stream_to_close.aclose()
|
||||
elif hasattr(stream_to_close, "close"):
|
||||
result = stream_to_close.close()
|
||||
if result is not None:
|
||||
await result
|
||||
except BaseException as e:
|
||||
verbose_logger.debug(
|
||||
"CustomStreamWrapper.aclose: error closing completion_stream: %s",
|
||||
e,
|
||||
)
|
||||
|
||||
def check_send_stream_usage(self, stream_options: Optional[dict]):
|
||||
return (
|
||||
stream_options is not None
|
||||
|
|
|
|||
|
|
@ -726,10 +726,12 @@ def _count_content_list(
|
|||
if thinking_text:
|
||||
num_tokens += count_function(thinking_text)
|
||||
else:
|
||||
content_type = (
|
||||
c.get("type", type(c).__name__) if isinstance(c, dict) else type(c).__name__
|
||||
)
|
||||
raise ValueError(
|
||||
f"Invalid content item type: {type(c).__name__}. "
|
||||
f"Expected str or dict with 'type' field. "
|
||||
f"Value: {c!r}"
|
||||
f"Invalid content item type: {content_type}. "
|
||||
f"Expected str or dict with 'type' field (text, image_url, tool_use, tool_result, thinking)."
|
||||
)
|
||||
return num_tokens
|
||||
except Exception as e:
|
||||
|
|
|
|||
|
|
@ -46,6 +46,7 @@ from litellm.types.llms.openai import (
|
|||
ChatCompletionToolCallChunk,
|
||||
ChatCompletionToolCallFunctionChunk,
|
||||
ChatCompletionToolParam,
|
||||
OpenAIChatCompletionFinishReason,
|
||||
OpenAIMcpServerTool,
|
||||
OpenAIWebSearchOptions,
|
||||
)
|
||||
|
|
@ -54,10 +55,7 @@ from litellm.types.utils import (
|
|||
CompletionTokensDetailsWrapper,
|
||||
)
|
||||
from litellm.types.utils import Message as LitellmMessage
|
||||
from litellm.types.utils import (
|
||||
PromptTokensDetailsWrapper,
|
||||
ServerToolUse,
|
||||
)
|
||||
from litellm.types.utils import PromptTokensDetailsWrapper, ServerToolUse
|
||||
from litellm.utils import (
|
||||
ModelResponse,
|
||||
Usage,
|
||||
|
|
@ -251,10 +249,14 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
|
||||
# All numeric/string/array constraints not supported by Anthropic
|
||||
unsupported_fields = {
|
||||
"maxItems", "minItems", # array constraints
|
||||
"minimum", "maximum", # numeric constraints
|
||||
"exclusiveMinimum", "exclusiveMaximum", # numeric constraints
|
||||
"minLength", "maxLength", # string constraints
|
||||
"maxItems",
|
||||
"minItems", # array constraints
|
||||
"minimum",
|
||||
"maximum", # numeric constraints
|
||||
"exclusiveMinimum",
|
||||
"exclusiveMaximum", # numeric constraints
|
||||
"minLength",
|
||||
"maxLength", # string constraints
|
||||
}
|
||||
|
||||
# Build description additions from removed constraints
|
||||
|
|
@ -844,7 +846,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
|
||||
@staticmethod
|
||||
def map_openai_context_management_to_anthropic(
|
||||
context_management: Union[List[Dict[str, Any]], Dict[str, Any]]
|
||||
context_management: Union[List[Dict[str, Any]], Dict[str, Any]],
|
||||
) -> Optional[Dict[str, Any]]:
|
||||
"""
|
||||
OpenAI format: [{"type": "compaction", "compact_threshold": 200000}]
|
||||
|
|
@ -876,19 +878,22 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
|
||||
entry_type = entry.get("type")
|
||||
if entry_type == "compaction":
|
||||
anthropic_edit: Dict[str, Any] = {
|
||||
"type": "compact_20260112"
|
||||
}
|
||||
anthropic_edit: Dict[str, Any] = {"type": "compact_20260112"}
|
||||
compact_threshold = entry.get("compact_threshold")
|
||||
# Rewrite to 'trigger' with correct nesting if threshold exists
|
||||
if compact_threshold is not None and isinstance(compact_threshold, (int, float)):
|
||||
if compact_threshold is not None and isinstance(
|
||||
compact_threshold, (int, float)
|
||||
):
|
||||
anthropic_edit["trigger"] = {
|
||||
"type": "input_tokens",
|
||||
"value": int(compact_threshold)
|
||||
"value": int(compact_threshold),
|
||||
}
|
||||
# Map any other keys by passthrough except handled ones
|
||||
for k in entry:
|
||||
if k not in {"type", "compact_threshold"}: # only passthrough other keys
|
||||
if k not in {
|
||||
"type",
|
||||
"compact_threshold",
|
||||
}: # only passthrough other keys
|
||||
anthropic_edit[k] = entry[k]
|
||||
|
||||
anthropic_edits.append(anthropic_edit)
|
||||
|
|
@ -911,10 +916,14 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
|
||||
for param, value in non_default_params.items():
|
||||
if param == "max_tokens":
|
||||
optional_params["max_tokens"] = value
|
||||
if param == "max_completion_tokens":
|
||||
optional_params["max_tokens"] = value
|
||||
if param == "tools":
|
||||
optional_params["max_tokens"] = (
|
||||
value if isinstance(value, int) else max(1, int(round(value)))
|
||||
)
|
||||
elif param == "max_completion_tokens":
|
||||
optional_params["max_tokens"] = (
|
||||
value if isinstance(value, int) else max(1, int(round(value)))
|
||||
)
|
||||
elif param == "tools":
|
||||
# check if optional params already has tools
|
||||
anthropic_tools, mcp_servers = self._map_tools(value)
|
||||
optional_params = self._add_tools_to_optional_params(
|
||||
|
|
@ -922,7 +931,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
)
|
||||
if mcp_servers:
|
||||
optional_params["mcp_servers"] = mcp_servers
|
||||
if param == "tool_choice" or param == "parallel_tool_calls":
|
||||
elif param == "tool_choice" or param == "parallel_tool_calls":
|
||||
_tool_choice: Optional[AnthropicMessagesToolChoice] = (
|
||||
self._map_tool_choice(
|
||||
tool_choice=non_default_params.get("tool_choice"),
|
||||
|
|
@ -932,17 +941,19 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
|
||||
if _tool_choice is not None:
|
||||
optional_params["tool_choice"] = _tool_choice
|
||||
if param == "stream" and value is True:
|
||||
elif param == "stream" and value is True:
|
||||
optional_params["stream"] = value
|
||||
if param == "stop" and (isinstance(value, str) or isinstance(value, list)):
|
||||
elif param == "stop" and (
|
||||
isinstance(value, str) or isinstance(value, list)
|
||||
):
|
||||
_value = self._map_stop_sequences(value)
|
||||
if _value is not None:
|
||||
optional_params["stop_sequences"] = _value
|
||||
if param == "temperature":
|
||||
elif param == "temperature":
|
||||
optional_params["temperature"] = value
|
||||
if param == "top_p":
|
||||
elif param == "top_p":
|
||||
optional_params["top_p"] = value
|
||||
if param == "response_format" and isinstance(value, dict):
|
||||
elif param == "response_format" and isinstance(value, dict):
|
||||
if any(
|
||||
substring in model
|
||||
for substring in {
|
||||
|
|
@ -982,14 +993,14 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
optional_params=optional_params, tools=[_tool]
|
||||
)
|
||||
optional_params["json_mode"] = True
|
||||
if (
|
||||
elif (
|
||||
param == "user"
|
||||
and value is not None
|
||||
and isinstance(value, str)
|
||||
and _valid_user_id(value) # anthropic fails on emails
|
||||
):
|
||||
optional_params["metadata"] = {"user_id": value}
|
||||
if param == "thinking":
|
||||
elif param == "thinking":
|
||||
optional_params["thinking"] = value
|
||||
elif param == "reasoning_effort" and isinstance(value, str):
|
||||
optional_params["thinking"] = AnthropicConfig._map_reasoning_effort(
|
||||
|
|
@ -1007,9 +1018,13 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
elif param == "context_management":
|
||||
# Supports both OpenAI list format and Anthropic dict format
|
||||
if isinstance(value, (list, dict)):
|
||||
anthropic_context_management = self.map_openai_context_management_to_anthropic(value)
|
||||
anthropic_context_management = (
|
||||
self.map_openai_context_management_to_anthropic(value)
|
||||
)
|
||||
if anthropic_context_management is not None:
|
||||
optional_params["context_management"] = anthropic_context_management
|
||||
optional_params["context_management"] = (
|
||||
anthropic_context_management
|
||||
)
|
||||
elif param == "speed" and isinstance(value, str):
|
||||
# Pass through Anthropic-specific speed parameter for fast mode
|
||||
optional_params["speed"] = value
|
||||
|
|
@ -1071,7 +1086,9 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
if not system_message_block["content"]:
|
||||
continue
|
||||
# Skip system messages containing x-anthropic-billing-header metadata
|
||||
if system_message_block["content"].startswith("x-anthropic-billing-header:"):
|
||||
if system_message_block["content"].startswith(
|
||||
"x-anthropic-billing-header:"
|
||||
):
|
||||
continue
|
||||
anthropic_system_message_content = AnthropicSystemMessageContent(
|
||||
type="text",
|
||||
|
|
@ -1091,7 +1108,11 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
if _content.get("type") == "text" and not text_value:
|
||||
continue
|
||||
# Skip system messages containing x-anthropic-billing-header metadata
|
||||
if _content.get("type") == "text" and text_value and text_value.startswith("x-anthropic-billing-header:"):
|
||||
if (
|
||||
_content.get("type") == "text"
|
||||
and text_value
|
||||
and text_value.startswith("x-anthropic-billing-header:")
|
||||
):
|
||||
continue
|
||||
anthropic_system_message_content = (
|
||||
AnthropicSystemMessageContent(
|
||||
|
|
@ -1201,7 +1222,8 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
# Add context management header if any other edits/entries exist
|
||||
if has_other:
|
||||
self._ensure_beta_header(
|
||||
headers, ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value
|
||||
headers,
|
||||
ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value,
|
||||
)
|
||||
|
||||
def update_headers_with_optional_anthropic_beta(
|
||||
|
|
@ -1227,7 +1249,8 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
ANTHROPIC_HOSTED_TOOLS.MEMORY.value
|
||||
):
|
||||
self._ensure_beta_header(
|
||||
headers, ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value
|
||||
headers,
|
||||
ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value,
|
||||
)
|
||||
if optional_params.get("context_management") is not None:
|
||||
self._ensure_context_management_beta_header(
|
||||
|
|
@ -1491,7 +1514,16 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
if thinking_content is not None:
|
||||
reasoning_content += thinking_content
|
||||
|
||||
return text_content, citations, thinking_blocks, reasoning_content, tool_calls, web_search_results, tool_results, compaction_blocks
|
||||
return (
|
||||
text_content,
|
||||
citations,
|
||||
thinking_blocks,
|
||||
reasoning_content,
|
||||
tool_calls,
|
||||
web_search_results,
|
||||
tool_results,
|
||||
compaction_blocks,
|
||||
)
|
||||
|
||||
def calculate_usage(
|
||||
self,
|
||||
|
|
@ -1576,7 +1608,11 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
)
|
||||
completion_token_details = CompletionTokensDetailsWrapper(
|
||||
reasoning_tokens=reasoning_tokens if reasoning_tokens > 0 else 0,
|
||||
text_tokens=completion_tokens - reasoning_tokens if reasoning_tokens > 0 else completion_tokens,
|
||||
text_tokens=(
|
||||
completion_tokens - reasoning_tokens
|
||||
if reasoning_tokens > 0
|
||||
else completion_tokens
|
||||
),
|
||||
)
|
||||
total_tokens = prompt_tokens + completion_tokens
|
||||
|
||||
|
|
@ -1696,8 +1732,9 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
"content"
|
||||
] # allow user to access raw anthropic tool calling response
|
||||
|
||||
model_response.choices[0].finish_reason = map_finish_reason(
|
||||
completion_response["stop_reason"]
|
||||
model_response.choices[0].finish_reason = cast(
|
||||
OpenAIChatCompletionFinishReason,
|
||||
map_finish_reason(completion_response["stop_reason"]),
|
||||
)
|
||||
|
||||
## CALCULATING USAGE
|
||||
|
|
|
|||
|
|
@ -330,7 +330,7 @@ class LiteLLMAiohttpTransport(AiohttpTransport):
|
|||
return httpx.Response(
|
||||
status_code=response.status,
|
||||
headers=response.headers,
|
||||
content=AiohttpResponseStream(response),
|
||||
stream=AiohttpResponseStream(response),
|
||||
request=request,
|
||||
)
|
||||
|
||||
|
|
|
|||
|
|
@ -1207,28 +1207,7 @@ def get_async_httpx_client(
|
|||
If not present, creates a new client
|
||||
|
||||
Caches the new client and returns it.
|
||||
|
||||
Note: When shared_session is provided, the cache is bypassed to ensure
|
||||
the user's session (with its trace_configs, connector settings, etc.)
|
||||
is used for the request.
|
||||
"""
|
||||
# When shared_session is provided, bypass cache and create a new handler
|
||||
# that uses the user's session directly. This preserves the user's
|
||||
# session configuration including trace_configs for aiohttp tracing.
|
||||
if shared_session is not None:
|
||||
verbose_logger.debug(
|
||||
f"shared_session provided (ID: {id(shared_session)}), bypassing client cache"
|
||||
)
|
||||
if params is not None:
|
||||
handler_params = {k: v for k, v in params.items() if k != "disable_aiohttp_transport"}
|
||||
handler_params["shared_session"] = shared_session
|
||||
return AsyncHTTPHandler(**handler_params)
|
||||
else:
|
||||
return AsyncHTTPHandler(
|
||||
timeout=httpx.Timeout(timeout=600.0, connect=5.0),
|
||||
shared_session=shared_session,
|
||||
)
|
||||
|
||||
_params_key_name = ""
|
||||
if params is not None:
|
||||
for key, value in params.items():
|
||||
|
|
@ -1255,10 +1234,12 @@ def get_async_httpx_client(
|
|||
if params is not None:
|
||||
# Filter out params that are only used for cache key, not for AsyncHTTPHandler.__init__
|
||||
handler_params = {k: v for k, v in params.items() if k != "disable_aiohttp_transport"}
|
||||
handler_params["shared_session"] = shared_session
|
||||
_new_client = AsyncHTTPHandler(**handler_params)
|
||||
else:
|
||||
_new_client = AsyncHTTPHandler(
|
||||
timeout=httpx.Timeout(timeout=600.0, connect=5.0),
|
||||
shared_session=shared_session,
|
||||
)
|
||||
|
||||
cache.set_cache(
|
||||
|
|
|
|||
|
|
@ -3,9 +3,10 @@ Common helpers / utils across al OpenAI endpoints
|
|||
"""
|
||||
|
||||
import hashlib
|
||||
import inspect
|
||||
import json
|
||||
import ssl
|
||||
from typing import Any, Dict, List, Literal, Optional, TYPE_CHECKING, Union
|
||||
from typing import TYPE_CHECKING, Any, Dict, List, Literal, Optional, Tuple, Union
|
||||
|
||||
import httpx
|
||||
import openai
|
||||
|
|
@ -23,6 +24,15 @@ from litellm.llms.custom_httpx.http_handler import (
|
|||
)
|
||||
|
||||
|
||||
def _get_client_init_params(cls: type) -> Tuple[str, ...]:
|
||||
"""Extract __init__ parameter names (excluding 'self') from a class."""
|
||||
return tuple(p for p in inspect.signature(cls.__init__).parameters if p != "self") # type: ignore[misc]
|
||||
|
||||
|
||||
_OPENAI_INIT_PARAMS: Tuple[str, ...] = _get_client_init_params(OpenAI)
|
||||
_AZURE_OPENAI_INIT_PARAMS: Tuple[str, ...] = _get_client_init_params(AzureOpenAI)
|
||||
|
||||
|
||||
class OpenAIError(BaseLLMException):
|
||||
def __init__(
|
||||
self,
|
||||
|
|
@ -159,12 +169,12 @@ class BaseOpenAILLM:
|
|||
f"is_async={client_initialization_params.get('is_async')}",
|
||||
]
|
||||
|
||||
LITELLM_CLIENT_SPECIFIC_PARAMS = [
|
||||
LITELLM_CLIENT_SPECIFIC_PARAMS = (
|
||||
"timeout",
|
||||
"max_retries",
|
||||
"organization",
|
||||
"api_base",
|
||||
]
|
||||
)
|
||||
openai_client_fields = (
|
||||
BaseOpenAILLM.get_openai_client_initialization_param_fields(
|
||||
client_type=client_type
|
||||
|
|
@ -181,20 +191,12 @@ class BaseOpenAILLM:
|
|||
@staticmethod
|
||||
def get_openai_client_initialization_param_fields(
|
||||
client_type: Literal["openai", "azure"]
|
||||
) -> List[str]:
|
||||
"""Returns a list of fields that are used to initialize the OpenAI client"""
|
||||
import inspect
|
||||
|
||||
from openai import AzureOpenAI, OpenAI
|
||||
|
||||
) -> Tuple[str, ...]:
|
||||
"""Returns a tuple of fields that are used to initialize the OpenAI client"""
|
||||
if client_type == "openai":
|
||||
signature = inspect.signature(OpenAI.__init__)
|
||||
return _OPENAI_INIT_PARAMS
|
||||
else:
|
||||
signature = inspect.signature(AzureOpenAI.__init__)
|
||||
|
||||
# Extract parameter names, excluding 'self'
|
||||
param_names = [param for param in signature.parameters if param != "self"]
|
||||
return param_names
|
||||
return _AZURE_OPENAI_INIT_PARAMS
|
||||
|
||||
@staticmethod
|
||||
def _get_async_http_client(
|
||||
|
|
@ -230,3 +232,5 @@ class BaseOpenAILLM:
|
|||
verify=ssl_config,
|
||||
follow_redirects=True,
|
||||
)
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -693,6 +693,7 @@ class OpenAIChatCompletion(BaseLLM, BaseOpenAILLM):
|
|||
organization=organization,
|
||||
drop_params=drop_params,
|
||||
stream_options=stream_options,
|
||||
shared_session=shared_session,
|
||||
)
|
||||
else:
|
||||
return self.acompletion(
|
||||
|
|
@ -1063,6 +1064,7 @@ class OpenAIChatCompletion(BaseLLM, BaseOpenAILLM):
|
|||
headers=None,
|
||||
drop_params: Optional[bool] = None,
|
||||
stream_options: Optional[dict] = None,
|
||||
shared_session: Optional["ClientSession"] = None,
|
||||
):
|
||||
response = None
|
||||
data = provider_config.transform_request(
|
||||
|
|
@ -1087,6 +1089,7 @@ class OpenAIChatCompletion(BaseLLM, BaseOpenAILLM):
|
|||
max_retries=max_retries,
|
||||
organization=organization,
|
||||
client=client,
|
||||
shared_session=shared_session,
|
||||
)
|
||||
## LOGGING
|
||||
logging_obj.pre_call(
|
||||
|
|
|
|||
|
|
@ -247,7 +247,7 @@ def completion( # noqa: PLR0915
|
|||
instances = [optional_params.copy()]
|
||||
instances[0]["prompt"] = prompt
|
||||
instances = [
|
||||
json_format.ParseDict(instance_dict, Value())
|
||||
json_format.ParseDict(instance_dict, Value()) # type: ignore[misc]
|
||||
for instance_dict in instances
|
||||
]
|
||||
# Will determine the API used based on async parameter
|
||||
|
|
@ -375,7 +375,7 @@ def completion( # noqa: PLR0915
|
|||
)
|
||||
llm_model = aiplatform.gapic.PredictionServiceClient(
|
||||
client_options=client_options,
|
||||
credentials=creds,
|
||||
credentials=creds, # type: ignore[arg-type]
|
||||
)
|
||||
request_str += f"llm_model = aiplatform.gapic.PredictionServiceClient(client_options={client_options}, credentials=...)\n"
|
||||
endpoint_path = llm_model.endpoint_path(
|
||||
|
|
@ -441,7 +441,7 @@ def completion( # noqa: PLR0915
|
|||
model_response.model = model
|
||||
## CALCULATING USAGE
|
||||
if model in litellm.vertex_language_models and response_obj is not None:
|
||||
model_response.choices[0].finish_reason = map_finish_reason(
|
||||
model_response.choices[0].finish_reason = map_finish_reason( # type: ignore[assignment]
|
||||
response_obj.candidates[0].finish_reason.name
|
||||
)
|
||||
usage = Usage(
|
||||
|
|
@ -614,7 +614,7 @@ async def async_completion( # noqa: PLR0915
|
|||
model_response.model = model
|
||||
## CALCULATING USAGE
|
||||
if model in litellm.vertex_language_models and response_obj is not None:
|
||||
model_response.choices[0].finish_reason = map_finish_reason(
|
||||
model_response.choices[0].finish_reason = map_finish_reason( # type: ignore[assignment]
|
||||
response_obj.candidates[0].finish_reason.name
|
||||
)
|
||||
usage = Usage(
|
||||
|
|
|
|||
|
|
@ -159,6 +159,7 @@ from .litellm_core_utils.fallback_utils import (
|
|||
completion_with_fallbacks,
|
||||
)
|
||||
from .litellm_core_utils.prompt_templates.common_utils import (
|
||||
add_system_prompt_to_messages,
|
||||
get_completion_messages,
|
||||
update_messages_with_model_file_ids,
|
||||
)
|
||||
|
|
@ -599,7 +600,7 @@ async def acompletion( # noqa: PLR0915
|
|||
# Add the context to the function
|
||||
ctx = contextvars.copy_context()
|
||||
func_with_context = partial(ctx.run, func)
|
||||
|
||||
|
||||
init_response = await loop.run_in_executor(None, func_with_context)
|
||||
if isinstance(init_response, dict) or isinstance(
|
||||
init_response, ModelResponse
|
||||
|
|
@ -939,7 +940,7 @@ def responses_api_bridge_check(
|
|||
model = model.replace("responses/", "")
|
||||
mode = "responses"
|
||||
model_info["mode"] = mode
|
||||
|
||||
|
||||
if web_search_options is not None and custom_llm_provider == "xai":
|
||||
model_info["mode"] = "responses"
|
||||
model = model.replace("responses/", "")
|
||||
|
|
@ -1108,9 +1109,7 @@ def completion( # type: ignore # noqa: PLR0915
|
|||
|
||||
skip_mcp_handler = kwargs.pop("_skip_mcp_handler", False)
|
||||
if not skip_mcp_handler and tools:
|
||||
from litellm.responses.mcp.chat_completions_handler import (
|
||||
acompletion_with_mcp,
|
||||
)
|
||||
from litellm.responses.mcp.chat_completions_handler import acompletion_with_mcp
|
||||
from litellm.responses.mcp.litellm_proxy_mcp_handler import (
|
||||
LiteLLM_Proxy_MCP_Handler,
|
||||
)
|
||||
|
|
@ -1245,6 +1244,7 @@ def completion( # type: ignore # noqa: PLR0915
|
|||
### PROMPT MANAGEMENT ###
|
||||
prompt_id = cast(Optional[str], kwargs.get("prompt_id", None))
|
||||
prompt_variables = cast(Optional[dict], kwargs.get("prompt_variables", None))
|
||||
litellm_system_prompt = kwargs.get("litellm_system_prompt", None)
|
||||
### COPY MESSAGES ### - related issue https://github.com/BerriAI/litellm/discussions/4489
|
||||
messages = get_completion_messages(
|
||||
messages=messages,
|
||||
|
|
@ -1276,6 +1276,14 @@ def completion( # type: ignore # noqa: PLR0915
|
|||
prompt_version=kwargs.get("prompt_version", None),
|
||||
)
|
||||
|
||||
### LITELLM SYSTEM PROMPT ###
|
||||
if litellm_system_prompt:
|
||||
messages = add_system_prompt_to_messages(
|
||||
messages=messages,
|
||||
system_prompt=litellm_system_prompt,
|
||||
merge_with_first_system=True,
|
||||
)
|
||||
|
||||
try:
|
||||
if base_url is not None:
|
||||
api_base = base_url
|
||||
|
|
@ -1558,7 +1566,9 @@ def completion( # type: ignore # noqa: PLR0915
|
|||
|
||||
## RESPONSES API BRIDGE LOGIC ## - check if model has 'mode: responses' in litellm.model_cost map
|
||||
model_info, model = responses_api_bridge_check(
|
||||
model=model, custom_llm_provider=custom_llm_provider, web_search_options=web_search_options
|
||||
model=model,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
web_search_options=web_search_options,
|
||||
)
|
||||
|
||||
if model_info.get("mode") == "responses":
|
||||
|
|
@ -2209,17 +2219,19 @@ def completion( # type: ignore # noqa: PLR0915
|
|||
elif custom_llm_provider == "a2a":
|
||||
# A2A (Agent-to-Agent) Protocol
|
||||
# Resolve agent configuration from registry if model format is "a2a/<agent-name>"
|
||||
api_base, api_key, headers = litellm.A2AConfig.resolve_agent_config_from_registry(
|
||||
model=model,
|
||||
api_base=api_base,
|
||||
api_key=api_key,
|
||||
headers=headers,
|
||||
optional_params=optional_params,
|
||||
api_base, api_key, headers = (
|
||||
litellm.A2AConfig.resolve_agent_config_from_registry(
|
||||
model=model,
|
||||
api_base=api_base,
|
||||
api_key=api_key,
|
||||
headers=headers,
|
||||
optional_params=optional_params,
|
||||
)
|
||||
)
|
||||
|
||||
|
||||
# Fall back to environment variables and defaults
|
||||
api_base = api_base or litellm.api_base or get_secret_str("A2A_API_BASE")
|
||||
|
||||
|
||||
if api_base is None:
|
||||
raise Exception(
|
||||
"api_base is required for A2A provider. "
|
||||
|
|
@ -4783,7 +4795,10 @@ def embedding( # noqa: PLR0915
|
|||
or custom_llm_provider == "together_ai"
|
||||
or custom_llm_provider == "nvidia_nim"
|
||||
or custom_llm_provider == "litellm_proxy"
|
||||
or (model in litellm.open_ai_embedding_models and custom_llm_provider is None)
|
||||
or (
|
||||
model in litellm.open_ai_embedding_models
|
||||
and custom_llm_provider is None
|
||||
)
|
||||
):
|
||||
api_base = (
|
||||
api_base
|
||||
|
|
@ -7239,7 +7254,11 @@ def stream_chunk_builder( # noqa: PLR0915
|
|||
continue
|
||||
|
||||
choice = chunk["choices"][0]
|
||||
delta_obj = choice.get("delta", {}) if isinstance(choice, dict) else getattr(choice, "delta", {})
|
||||
delta_obj = (
|
||||
choice.get("delta", {})
|
||||
if isinstance(choice, dict)
|
||||
else getattr(choice, "delta", {})
|
||||
)
|
||||
if isinstance(delta_obj, dict):
|
||||
delta = delta_obj
|
||||
elif hasattr(delta_obj, "model_dump"):
|
||||
|
|
@ -7266,7 +7285,9 @@ def stream_chunk_builder( # noqa: PLR0915
|
|||
|
||||
if is_simple_text_stream:
|
||||
if simple_content_parts:
|
||||
response["choices"][0]["message"]["content"] = "".join(simple_content_parts)
|
||||
response["choices"][0]["message"]["content"] = "".join(
|
||||
simple_content_parts
|
||||
)
|
||||
completion_output = get_content_from_model_response(response)
|
||||
usage = processor.calculate_usage(
|
||||
chunks=chunks,
|
||||
|
|
@ -7291,7 +7312,9 @@ def stream_chunk_builder( # noqa: PLR0915
|
|||
|
||||
if litellm.include_cost_in_streaming_usage and logging_obj is not None:
|
||||
setattr(
|
||||
usage, "cost", logging_obj._response_cost_calculator(result=response)
|
||||
usage,
|
||||
"cost",
|
||||
logging_obj._response_cost_calculator(result=response),
|
||||
)
|
||||
return response
|
||||
|
||||
|
|
@ -7504,6 +7527,7 @@ def __getattr__(name: str) -> Any:
|
|||
# before loading tiktoken, ensuring the local cache is used
|
||||
# instead of downloading from the internet
|
||||
from litellm._lazy_imports import _get_default_encoding
|
||||
|
||||
_encoding = _get_default_encoding()
|
||||
# Cache it in the module's __dict__ for subsequent accesses
|
||||
import sys
|
||||
|
|
|
|||
File diff suppressed because one or more lines are too long
|
|
@ -1,30 +1,31 @@
|
|||
1:"$Sreact.fragment"
|
||||
2:I[347257,["/litellm-asset-prefix/_next/static/chunks/d96012bcfc98706a.js","/litellm-asset-prefix/_next/static/chunks/dbca964212122d58.js"],"ClientPageRoot"]
|
||||
3:I[952683,["/litellm-asset-prefix/_next/static/chunks/26adfa4e8ffc85c7.js","/litellm-asset-prefix/_next/static/chunks/e8ed72789c2b42ff.js","/litellm-asset-prefix/_next/static/chunks/9f5ccd929375c1d6.js","/litellm-asset-prefix/_next/static/chunks/e3bc795c751bb99a.js","/litellm-asset-prefix/_next/static/chunks/1fe0596a309ad6cf.js","/litellm-asset-prefix/_next/static/chunks/c93c5c533dba84d1.js","/litellm-asset-prefix/_next/static/chunks/403c4d96324c23a6.js","/litellm-asset-prefix/_next/static/chunks/5f9c3b92a016f382.js","/litellm-asset-prefix/_next/static/chunks/58b9eb1766fba8e0.js","/litellm-asset-prefix/_next/static/chunks/d979defcb5b51fb7.js","/litellm-asset-prefix/_next/static/chunks/4188d520ca4e5f2b.js","/litellm-asset-prefix/_next/static/chunks/721827ff379ec15b.js","/litellm-asset-prefix/_next/static/chunks/fe5201571c777f09.js","/litellm-asset-prefix/_next/static/chunks/55e4fdc727df0383.js","/litellm-asset-prefix/_next/static/chunks/134f728fa7099e3e.js","/litellm-asset-prefix/_next/static/chunks/fe750aa0bf04912c.js","/litellm-asset-prefix/_next/static/chunks/7b788dd93ad868b3.js","/litellm-asset-prefix/_next/static/chunks/7d4cded1a1238581.js","/litellm-asset-prefix/_next/static/chunks/d64d74932cb225a3.js","/litellm-asset-prefix/_next/static/chunks/1add24430679f529.js","/litellm-asset-prefix/_next/static/chunks/2eae7b77b053b120.js","/litellm-asset-prefix/_next/static/chunks/457923c551f21385.js","/litellm-asset-prefix/_next/static/chunks/1ab4ccc7c0ba9eff.js","/litellm-asset-prefix/_next/static/chunks/88c74f8b4b20d25a.js","/litellm-asset-prefix/_next/static/chunks/0a671fedee641c02.js","/litellm-asset-prefix/_next/static/chunks/47e3c15dd006beba.js","/litellm-asset-prefix/_next/static/chunks/ae66f72b6e883cde.js","/litellm-asset-prefix/_next/static/chunks/e2b3b9219ce71314.js","/litellm-asset-prefix/_next/static/chunks/3b30ab8eaa03bc21.js","/litellm-asset-prefix/_next/static/chunks/99cf9cf99df5ccfc.js","/litellm-asset-prefix/_next/static/chunks/fe1ed23b45deb0ac.js","/litellm-asset-prefix/_next/static/chunks/08e65ab952d9546d.js","/litellm-asset-prefix/_next/static/chunks/c7b74067c01ee971.js","/litellm-asset-prefix/_next/static/chunks/1bda0a8545f524a8.js","/litellm-asset-prefix/_next/static/chunks/bee0c7dc52171fbb.js","/litellm-asset-prefix/_next/static/chunks/b6b337cd7d3ee9b2.js","/litellm-asset-prefix/_next/static/chunks/8f205045de362d9f.js","/litellm-asset-prefix/_next/static/chunks/450ebd094f4fa24d.js","/litellm-asset-prefix/_next/static/chunks/00ff280cdb7d7ee5.js","/litellm-asset-prefix/_next/static/chunks/0a65da2cd24e2ab6.js","/litellm-asset-prefix/_next/static/chunks/1df04fce056b1606.js","/litellm-asset-prefix/_next/static/chunks/496b84010c33cf69.js","/litellm-asset-prefix/_next/static/chunks/a382857dbbcea5d1.js","/litellm-asset-prefix/_next/static/chunks/edf7d866729d3369.js","/litellm-asset-prefix/_next/static/chunks/8c9ac5fb28e0d0fc.js","/litellm-asset-prefix/_next/static/chunks/8992001a9a91bc67.js","/litellm-asset-prefix/_next/static/chunks/2971c4658f1bcd7d.js","/litellm-asset-prefix/_next/static/chunks/6c4c97f1ea6e7d77.js","/litellm-asset-prefix/_next/static/chunks/e8718f949e42598e.js","/litellm-asset-prefix/_next/static/chunks/7e417dd24c8becd0.js","/litellm-asset-prefix/_next/static/chunks/4980372eaa37b78b.js","/litellm-asset-prefix/_next/static/chunks/8354d717e34ebd6f.js","/litellm-asset-prefix/_next/static/chunks/4d8f72e8b48a564a.js","/litellm-asset-prefix/_next/static/chunks/4030260fa65452ec.js","/litellm-asset-prefix/_next/static/chunks/ba3835d0e18215e5.js"],"default"]
|
||||
1a:I[897367,["/litellm-asset-prefix/_next/static/chunks/d96012bcfc98706a.js","/litellm-asset-prefix/_next/static/chunks/dbca964212122d58.js"],"OutletBoundary"]
|
||||
1b:"$Sreact.suspense"
|
||||
3:I[952683,["/litellm-asset-prefix/_next/static/chunks/26adfa4e8ffc85c7.js","/litellm-asset-prefix/_next/static/chunks/e8ed72789c2b42ff.js","/litellm-asset-prefix/_next/static/chunks/ad68dd123ab47eda.js","/litellm-asset-prefix/_next/static/chunks/dea8a22e13558d5a.js","/litellm-asset-prefix/_next/static/chunks/1fe0596a309ad6cf.js","/litellm-asset-prefix/_next/static/chunks/2ce4aba43ddc02ec.js","/litellm-asset-prefix/_next/static/chunks/90ee99692db4fdaa.js","/litellm-asset-prefix/_next/static/chunks/134f728fa7099e3e.js","/litellm-asset-prefix/_next/static/chunks/5f9c3b92a016f382.js","/litellm-asset-prefix/_next/static/chunks/7b788dd93ad868b3.js","/litellm-asset-prefix/_next/static/chunks/e3bc795c751bb99a.js","/litellm-asset-prefix/_next/static/chunks/9ffb8ddd0c9a7c31.js","/litellm-asset-prefix/_next/static/chunks/620d19e33d27e328.js","/litellm-asset-prefix/_next/static/chunks/0a671fedee641c02.js","/litellm-asset-prefix/_next/static/chunks/3b30ab8eaa03bc21.js","/litellm-asset-prefix/_next/static/chunks/fe750aa0bf04912c.js","/litellm-asset-prefix/_next/static/chunks/c95c1ec38f9d4c79.js","/litellm-asset-prefix/_next/static/chunks/00ff280cdb7d7ee5.js","/litellm-asset-prefix/_next/static/chunks/cda0969cf986d041.js","/litellm-asset-prefix/_next/static/chunks/1ab49d0a71eaa7f0.js","/litellm-asset-prefix/_next/static/chunks/4188d520ca4e5f2b.js","/litellm-asset-prefix/_next/static/chunks/d64d74932cb225a3.js","/litellm-asset-prefix/_next/static/chunks/64f1a2ef9113d86f.js","/litellm-asset-prefix/_next/static/chunks/88c74f8b4b20d25a.js","/litellm-asset-prefix/_next/static/chunks/fe5201571c777f09.js","/litellm-asset-prefix/_next/static/chunks/e8718f949e42598e.js","/litellm-asset-prefix/_next/static/chunks/24b1d0970a71eaa1.js","/litellm-asset-prefix/_next/static/chunks/8b39aef25ad05cb7.js","/litellm-asset-prefix/_next/static/chunks/6c4c97f1ea6e7d77.js","/litellm-asset-prefix/_next/static/chunks/717233091bfa29a6.js","/litellm-asset-prefix/_next/static/chunks/8992001a9a91bc67.js","/litellm-asset-prefix/_next/static/chunks/7e417dd24c8becd0.js","/litellm-asset-prefix/_next/static/chunks/c7b74067c01ee971.js","/litellm-asset-prefix/_next/static/chunks/496b84010c33cf69.js","/litellm-asset-prefix/_next/static/chunks/9dfb1f95871ccc9b.js","/litellm-asset-prefix/_next/static/chunks/99cf9cf99df5ccfc.js","/litellm-asset-prefix/_next/static/chunks/7d4cded1a1238581.js","/litellm-asset-prefix/_next/static/chunks/f9641e47d9945775.js","/litellm-asset-prefix/_next/static/chunks/0a65da2cd24e2ab6.js","/litellm-asset-prefix/_next/static/chunks/6a1d474f77e2682d.js","/litellm-asset-prefix/_next/static/chunks/93a33e3820a464ce.js","/litellm-asset-prefix/_next/static/chunks/a9600c08caec613f.js","/litellm-asset-prefix/_next/static/chunks/457923c551f21385.js","/litellm-asset-prefix/_next/static/chunks/fd04bd81ed67693a.js","/litellm-asset-prefix/_next/static/chunks/47812e8f19218c74.js","/litellm-asset-prefix/_next/static/chunks/8354d717e34ebd6f.js","/litellm-asset-prefix/_next/static/chunks/5a9194d7fc126b21.js","/litellm-asset-prefix/_next/static/chunks/2971c4658f1bcd7d.js","/litellm-asset-prefix/_next/static/chunks/1ab4ccc7c0ba9eff.js","/litellm-asset-prefix/_next/static/chunks/d4010df7b41ffdaa.js","/litellm-asset-prefix/_next/static/chunks/4980372eaa37b78b.js","/litellm-asset-prefix/_next/static/chunks/b023cd29f09b6fc7.js","/litellm-asset-prefix/_next/static/chunks/47e3c15dd006beba.js","/litellm-asset-prefix/_next/static/chunks/450ebd094f4fa24d.js","/litellm-asset-prefix/_next/static/chunks/1aeb67c826164bff.js","/litellm-asset-prefix/_next/static/chunks/975de62a103e2bc2.js"],"default"]
|
||||
1b:I[897367,["/litellm-asset-prefix/_next/static/chunks/d96012bcfc98706a.js","/litellm-asset-prefix/_next/static/chunks/dbca964212122d58.js"],"OutletBoundary"]
|
||||
1c:"$Sreact.suspense"
|
||||
:HL["/litellm-asset-prefix/_next/static/chunks/3f3fa56b5786d58c.css","style"]
|
||||
0:{"buildId":"w3I6ZteDnT32i9JBryDMD","rsc":["$","$1","c",{"children":[["$","$L2",null,{"Component":"$3","serverProvidedParams":{"searchParams":{},"params":{},"promises":["$@4","$@5"]}}],[["$","link","0",{"rel":"stylesheet","href":"/litellm-asset-prefix/_next/static/chunks/3f3fa56b5786d58c.css","precedence":"next"}],["$","script","script-0",{"src":"/litellm-asset-prefix/_next/static/chunks/9f5ccd929375c1d6.js","async":true}],["$","script","script-1",{"src":"/litellm-asset-prefix/_next/static/chunks/e3bc795c751bb99a.js","async":true}],["$","script","script-2",{"src":"/litellm-asset-prefix/_next/static/chunks/1fe0596a309ad6cf.js","async":true}],["$","script","script-3",{"src":"/litellm-asset-prefix/_next/static/chunks/c93c5c533dba84d1.js","async":true}],["$","script","script-4",{"src":"/litellm-asset-prefix/_next/static/chunks/403c4d96324c23a6.js","async":true}],["$","script","script-5",{"src":"/litellm-asset-prefix/_next/static/chunks/5f9c3b92a016f382.js","async":true}],["$","script","script-6",{"src":"/litellm-asset-prefix/_next/static/chunks/58b9eb1766fba8e0.js","async":true}],["$","script","script-7",{"src":"/litellm-asset-prefix/_next/static/chunks/d979defcb5b51fb7.js","async":true}],["$","script","script-8",{"src":"/litellm-asset-prefix/_next/static/chunks/4188d520ca4e5f2b.js","async":true}],["$","script","script-9",{"src":"/litellm-asset-prefix/_next/static/chunks/721827ff379ec15b.js","async":true}],["$","script","script-10",{"src":"/litellm-asset-prefix/_next/static/chunks/fe5201571c777f09.js","async":true}],["$","script","script-11",{"src":"/litellm-asset-prefix/_next/static/chunks/55e4fdc727df0383.js","async":true}],["$","script","script-12",{"src":"/litellm-asset-prefix/_next/static/chunks/134f728fa7099e3e.js","async":true}],["$","script","script-13",{"src":"/litellm-asset-prefix/_next/static/chunks/fe750aa0bf04912c.js","async":true}],["$","script","script-14",{"src":"/litellm-asset-prefix/_next/static/chunks/7b788dd93ad868b3.js","async":true}],["$","script","script-15",{"src":"/litellm-asset-prefix/_next/static/chunks/7d4cded1a1238581.js","async":true}],["$","script","script-16",{"src":"/litellm-asset-prefix/_next/static/chunks/d64d74932cb225a3.js","async":true}],["$","script","script-17",{"src":"/litellm-asset-prefix/_next/static/chunks/1add24430679f529.js","async":true}],["$","script","script-18",{"src":"/litellm-asset-prefix/_next/static/chunks/2eae7b77b053b120.js","async":true}],["$","script","script-19",{"src":"/litellm-asset-prefix/_next/static/chunks/457923c551f21385.js","async":true}],["$","script","script-20",{"src":"/litellm-asset-prefix/_next/static/chunks/1ab4ccc7c0ba9eff.js","async":true}],["$","script","script-21",{"src":"/litellm-asset-prefix/_next/static/chunks/88c74f8b4b20d25a.js","async":true}],["$","script","script-22",{"src":"/litellm-asset-prefix/_next/static/chunks/0a671fedee641c02.js","async":true}],["$","script","script-23",{"src":"/litellm-asset-prefix/_next/static/chunks/47e3c15dd006beba.js","async":true}],["$","script","script-24",{"src":"/litellm-asset-prefix/_next/static/chunks/ae66f72b6e883cde.js","async":true}],["$","script","script-25",{"src":"/litellm-asset-prefix/_next/static/chunks/e2b3b9219ce71314.js","async":true}],["$","script","script-26",{"src":"/litellm-asset-prefix/_next/static/chunks/3b30ab8eaa03bc21.js","async":true}],["$","script","script-27",{"src":"/litellm-asset-prefix/_next/static/chunks/99cf9cf99df5ccfc.js","async":true}],["$","script","script-28",{"src":"/litellm-asset-prefix/_next/static/chunks/fe1ed23b45deb0ac.js","async":true}],["$","script","script-29",{"src":"/litellm-asset-prefix/_next/static/chunks/08e65ab952d9546d.js","async":true}],["$","script","script-30",{"src":"/litellm-asset-prefix/_next/static/chunks/c7b74067c01ee971.js","async":true}],["$","script","script-31",{"src":"/litellm-asset-prefix/_next/static/chunks/1bda0a8545f524a8.js","async":true}],["$","script","script-32",{"src":"/litellm-asset-prefix/_next/static/chunks/bee0c7dc52171fbb.js","async":true}],["$","script","script-33",{"src":"/litellm-asset-prefix/_next/static/chunks/b6b337cd7d3ee9b2.js","async":true}],"$L6","$L7","$L8","$L9","$La","$Lb","$Lc","$Ld","$Le","$Lf","$L10","$L11","$L12","$L13","$L14","$L15","$L16","$L17","$L18"],"$L19"]}],"loading":null,"isPartial":false}
|
||||
0:{"buildId":"62sKsiTJhIKKiZmdKo1av","rsc":["$","$1","c",{"children":[["$","$L2",null,{"Component":"$3","serverProvidedParams":{"searchParams":{},"params":{},"promises":["$@4","$@5"]}}],[["$","link","0",{"rel":"stylesheet","href":"/litellm-asset-prefix/_next/static/chunks/3f3fa56b5786d58c.css","precedence":"next"}],["$","script","script-0",{"src":"/litellm-asset-prefix/_next/static/chunks/ad68dd123ab47eda.js","async":true}],["$","script","script-1",{"src":"/litellm-asset-prefix/_next/static/chunks/dea8a22e13558d5a.js","async":true}],["$","script","script-2",{"src":"/litellm-asset-prefix/_next/static/chunks/1fe0596a309ad6cf.js","async":true}],["$","script","script-3",{"src":"/litellm-asset-prefix/_next/static/chunks/2ce4aba43ddc02ec.js","async":true}],["$","script","script-4",{"src":"/litellm-asset-prefix/_next/static/chunks/90ee99692db4fdaa.js","async":true}],["$","script","script-5",{"src":"/litellm-asset-prefix/_next/static/chunks/134f728fa7099e3e.js","async":true}],["$","script","script-6",{"src":"/litellm-asset-prefix/_next/static/chunks/5f9c3b92a016f382.js","async":true}],["$","script","script-7",{"src":"/litellm-asset-prefix/_next/static/chunks/7b788dd93ad868b3.js","async":true}],["$","script","script-8",{"src":"/litellm-asset-prefix/_next/static/chunks/e3bc795c751bb99a.js","async":true}],["$","script","script-9",{"src":"/litellm-asset-prefix/_next/static/chunks/9ffb8ddd0c9a7c31.js","async":true}],["$","script","script-10",{"src":"/litellm-asset-prefix/_next/static/chunks/620d19e33d27e328.js","async":true}],["$","script","script-11",{"src":"/litellm-asset-prefix/_next/static/chunks/0a671fedee641c02.js","async":true}],["$","script","script-12",{"src":"/litellm-asset-prefix/_next/static/chunks/3b30ab8eaa03bc21.js","async":true}],["$","script","script-13",{"src":"/litellm-asset-prefix/_next/static/chunks/fe750aa0bf04912c.js","async":true}],["$","script","script-14",{"src":"/litellm-asset-prefix/_next/static/chunks/c95c1ec38f9d4c79.js","async":true}],["$","script","script-15",{"src":"/litellm-asset-prefix/_next/static/chunks/00ff280cdb7d7ee5.js","async":true}],["$","script","script-16",{"src":"/litellm-asset-prefix/_next/static/chunks/cda0969cf986d041.js","async":true}],["$","script","script-17",{"src":"/litellm-asset-prefix/_next/static/chunks/1ab49d0a71eaa7f0.js","async":true}],["$","script","script-18",{"src":"/litellm-asset-prefix/_next/static/chunks/4188d520ca4e5f2b.js","async":true}],["$","script","script-19",{"src":"/litellm-asset-prefix/_next/static/chunks/d64d74932cb225a3.js","async":true}],["$","script","script-20",{"src":"/litellm-asset-prefix/_next/static/chunks/64f1a2ef9113d86f.js","async":true}],["$","script","script-21",{"src":"/litellm-asset-prefix/_next/static/chunks/88c74f8b4b20d25a.js","async":true}],["$","script","script-22",{"src":"/litellm-asset-prefix/_next/static/chunks/fe5201571c777f09.js","async":true}],["$","script","script-23",{"src":"/litellm-asset-prefix/_next/static/chunks/e8718f949e42598e.js","async":true}],["$","script","script-24",{"src":"/litellm-asset-prefix/_next/static/chunks/24b1d0970a71eaa1.js","async":true}],["$","script","script-25",{"src":"/litellm-asset-prefix/_next/static/chunks/8b39aef25ad05cb7.js","async":true}],["$","script","script-26",{"src":"/litellm-asset-prefix/_next/static/chunks/6c4c97f1ea6e7d77.js","async":true}],["$","script","script-27",{"src":"/litellm-asset-prefix/_next/static/chunks/717233091bfa29a6.js","async":true}],["$","script","script-28",{"src":"/litellm-asset-prefix/_next/static/chunks/8992001a9a91bc67.js","async":true}],["$","script","script-29",{"src":"/litellm-asset-prefix/_next/static/chunks/7e417dd24c8becd0.js","async":true}],["$","script","script-30",{"src":"/litellm-asset-prefix/_next/static/chunks/c7b74067c01ee971.js","async":true}],["$","script","script-31",{"src":"/litellm-asset-prefix/_next/static/chunks/496b84010c33cf69.js","async":true}],["$","script","script-32",{"src":"/litellm-asset-prefix/_next/static/chunks/9dfb1f95871ccc9b.js","async":true}],["$","script","script-33",{"src":"/litellm-asset-prefix/_next/static/chunks/99cf9cf99df5ccfc.js","async":true}],"$L6","$L7","$L8","$L9","$La","$Lb","$Lc","$Ld","$Le","$Lf","$L10","$L11","$L12","$L13","$L14","$L15","$L16","$L17","$L18","$L19"],"$L1a"]}],"loading":null,"isPartial":false}
|
||||
4:{}
|
||||
5:"$0:rsc:props:children:0:props:serverProvidedParams:params"
|
||||
6:["$","script","script-34",{"src":"/litellm-asset-prefix/_next/static/chunks/8f205045de362d9f.js","async":true}]
|
||||
7:["$","script","script-35",{"src":"/litellm-asset-prefix/_next/static/chunks/450ebd094f4fa24d.js","async":true}]
|
||||
8:["$","script","script-36",{"src":"/litellm-asset-prefix/_next/static/chunks/00ff280cdb7d7ee5.js","async":true}]
|
||||
9:["$","script","script-37",{"src":"/litellm-asset-prefix/_next/static/chunks/0a65da2cd24e2ab6.js","async":true}]
|
||||
a:["$","script","script-38",{"src":"/litellm-asset-prefix/_next/static/chunks/1df04fce056b1606.js","async":true}]
|
||||
b:["$","script","script-39",{"src":"/litellm-asset-prefix/_next/static/chunks/496b84010c33cf69.js","async":true}]
|
||||
c:["$","script","script-40",{"src":"/litellm-asset-prefix/_next/static/chunks/a382857dbbcea5d1.js","async":true}]
|
||||
d:["$","script","script-41",{"src":"/litellm-asset-prefix/_next/static/chunks/edf7d866729d3369.js","async":true}]
|
||||
e:["$","script","script-42",{"src":"/litellm-asset-prefix/_next/static/chunks/8c9ac5fb28e0d0fc.js","async":true}]
|
||||
f:["$","script","script-43",{"src":"/litellm-asset-prefix/_next/static/chunks/8992001a9a91bc67.js","async":true}]
|
||||
10:["$","script","script-44",{"src":"/litellm-asset-prefix/_next/static/chunks/2971c4658f1bcd7d.js","async":true}]
|
||||
11:["$","script","script-45",{"src":"/litellm-asset-prefix/_next/static/chunks/6c4c97f1ea6e7d77.js","async":true}]
|
||||
12:["$","script","script-46",{"src":"/litellm-asset-prefix/_next/static/chunks/e8718f949e42598e.js","async":true}]
|
||||
13:["$","script","script-47",{"src":"/litellm-asset-prefix/_next/static/chunks/7e417dd24c8becd0.js","async":true}]
|
||||
6:["$","script","script-34",{"src":"/litellm-asset-prefix/_next/static/chunks/7d4cded1a1238581.js","async":true}]
|
||||
7:["$","script","script-35",{"src":"/litellm-asset-prefix/_next/static/chunks/f9641e47d9945775.js","async":true}]
|
||||
8:["$","script","script-36",{"src":"/litellm-asset-prefix/_next/static/chunks/0a65da2cd24e2ab6.js","async":true}]
|
||||
9:["$","script","script-37",{"src":"/litellm-asset-prefix/_next/static/chunks/6a1d474f77e2682d.js","async":true}]
|
||||
a:["$","script","script-38",{"src":"/litellm-asset-prefix/_next/static/chunks/93a33e3820a464ce.js","async":true}]
|
||||
b:["$","script","script-39",{"src":"/litellm-asset-prefix/_next/static/chunks/a9600c08caec613f.js","async":true}]
|
||||
c:["$","script","script-40",{"src":"/litellm-asset-prefix/_next/static/chunks/457923c551f21385.js","async":true}]
|
||||
d:["$","script","script-41",{"src":"/litellm-asset-prefix/_next/static/chunks/fd04bd81ed67693a.js","async":true}]
|
||||
e:["$","script","script-42",{"src":"/litellm-asset-prefix/_next/static/chunks/47812e8f19218c74.js","async":true}]
|
||||
f:["$","script","script-43",{"src":"/litellm-asset-prefix/_next/static/chunks/8354d717e34ebd6f.js","async":true}]
|
||||
10:["$","script","script-44",{"src":"/litellm-asset-prefix/_next/static/chunks/5a9194d7fc126b21.js","async":true}]
|
||||
11:["$","script","script-45",{"src":"/litellm-asset-prefix/_next/static/chunks/2971c4658f1bcd7d.js","async":true}]
|
||||
12:["$","script","script-46",{"src":"/litellm-asset-prefix/_next/static/chunks/1ab4ccc7c0ba9eff.js","async":true}]
|
||||
13:["$","script","script-47",{"src":"/litellm-asset-prefix/_next/static/chunks/d4010df7b41ffdaa.js","async":true}]
|
||||
14:["$","script","script-48",{"src":"/litellm-asset-prefix/_next/static/chunks/4980372eaa37b78b.js","async":true}]
|
||||
15:["$","script","script-49",{"src":"/litellm-asset-prefix/_next/static/chunks/8354d717e34ebd6f.js","async":true}]
|
||||
16:["$","script","script-50",{"src":"/litellm-asset-prefix/_next/static/chunks/4d8f72e8b48a564a.js","async":true}]
|
||||
17:["$","script","script-51",{"src":"/litellm-asset-prefix/_next/static/chunks/4030260fa65452ec.js","async":true}]
|
||||
18:["$","script","script-52",{"src":"/litellm-asset-prefix/_next/static/chunks/ba3835d0e18215e5.js","async":true}]
|
||||
19:["$","$L1a",null,{"children":["$","$1b",null,{"name":"Next.MetadataOutlet","children":"$@1c"}]}]
|
||||
1c:null
|
||||
15:["$","script","script-49",{"src":"/litellm-asset-prefix/_next/static/chunks/b023cd29f09b6fc7.js","async":true}]
|
||||
16:["$","script","script-50",{"src":"/litellm-asset-prefix/_next/static/chunks/47e3c15dd006beba.js","async":true}]
|
||||
17:["$","script","script-51",{"src":"/litellm-asset-prefix/_next/static/chunks/450ebd094f4fa24d.js","async":true}]
|
||||
18:["$","script","script-52",{"src":"/litellm-asset-prefix/_next/static/chunks/1aeb67c826164bff.js","async":true}]
|
||||
19:["$","script","script-53",{"src":"/litellm-asset-prefix/_next/static/chunks/975de62a103e2bc2.js","async":true}]
|
||||
1a:["$","$L1b",null,{"children":["$","$1c",null,{"name":"Next.MetadataOutlet","children":"$@1d"}]}]
|
||||
1d:null
|
||||
|
|
|
|||
File diff suppressed because one or more lines are too long
|
|
@ -3,4 +3,4 @@
|
|||
3:I[897367,["/litellm-asset-prefix/_next/static/chunks/d96012bcfc98706a.js","/litellm-asset-prefix/_next/static/chunks/dbca964212122d58.js"],"MetadataBoundary"]
|
||||
4:"$Sreact.suspense"
|
||||
5:I[27201,["/litellm-asset-prefix/_next/static/chunks/d96012bcfc98706a.js","/litellm-asset-prefix/_next/static/chunks/dbca964212122d58.js"],"IconMark"]
|
||||
0:{"buildId":"w3I6ZteDnT32i9JBryDMD","rsc":["$","$1","h",{"children":[null,["$","$L2",null,{"children":[["$","meta","0",{"charSet":"utf-8"}],["$","meta","1",{"name":"viewport","content":"width=device-width, initial-scale=1"}]]}],["$","div",null,{"hidden":true,"children":["$","$L3",null,{"children":["$","$4",null,{"name":"Next.Metadata","children":[["$","title","0",{"children":"LiteLLM Dashboard"}],["$","meta","1",{"name":"description","content":"LiteLLM Proxy Admin UI"}],["$","link","2",{"rel":"icon","href":"/favicon.ico?favicon.1d32c690.ico","sizes":"48x48","type":"image/x-icon"}],["$","link","3",{"rel":"icon","href":"./favicon.ico"}],["$","$L5","4",{}]]}]}]}],["$","meta",null,{"name":"next-size-adjust","content":""}]]}],"loading":null,"isPartial":false}
|
||||
0:{"buildId":"62sKsiTJhIKKiZmdKo1av","rsc":["$","$1","h",{"children":[null,["$","$L2",null,{"children":[["$","meta","0",{"charSet":"utf-8"}],["$","meta","1",{"name":"viewport","content":"width=device-width, initial-scale=1"}]]}],["$","div",null,{"hidden":true,"children":["$","$L3",null,{"children":["$","$4",null,{"name":"Next.Metadata","children":[["$","title","0",{"children":"LiteLLM Dashboard"}],["$","meta","1",{"name":"description","content":"LiteLLM Proxy Admin UI"}],["$","link","2",{"rel":"icon","href":"/favicon.ico?favicon.1d32c690.ico","sizes":"48x48","type":"image/x-icon"}],["$","link","3",{"rel":"icon","href":"./favicon.ico"}],["$","$L5","4",{}]]}]}]}],["$","meta",null,{"name":"next-size-adjust","content":""}]]}],"loading":null,"isPartial":false}
|
||||
|
|
|
|||
|
|
@ -3,5 +3,5 @@
|
|||
3:I[339756,["/litellm-asset-prefix/_next/static/chunks/d96012bcfc98706a.js","/litellm-asset-prefix/_next/static/chunks/dbca964212122d58.js"],"default"]
|
||||
4:I[837457,["/litellm-asset-prefix/_next/static/chunks/d96012bcfc98706a.js","/litellm-asset-prefix/_next/static/chunks/dbca964212122d58.js"],"default"]
|
||||
:HL["/litellm-asset-prefix/_next/static/chunks/4e20891f2fd03463.css","style"]
|
||||
:HL["/litellm-asset-prefix/_next/static/chunks/a601549506e6d96f.css","style"]
|
||||
0:{"buildId":"w3I6ZteDnT32i9JBryDMD","rsc":["$","$1","c",{"children":[[["$","link","0",{"rel":"stylesheet","href":"/litellm-asset-prefix/_next/static/chunks/4e20891f2fd03463.css","precedence":"next"}],["$","link","1",{"rel":"stylesheet","href":"/litellm-asset-prefix/_next/static/chunks/a601549506e6d96f.css","precedence":"next"}],["$","script","script-0",{"src":"/litellm-asset-prefix/_next/static/chunks/26adfa4e8ffc85c7.js","async":true}],["$","script","script-1",{"src":"/litellm-asset-prefix/_next/static/chunks/e8ed72789c2b42ff.js","async":true}]],["$","html",null,{"lang":"en","children":["$","body",null,{"className":"inter_5972bc34-module__OU16Qa__className","children":["$","$L2",null,{"children":["$","$L3",null,{"parallelRouterKey":"children","template":["$","$L4",null,{}],"notFound":[[["$","title",null,{"children":"404: This page could not be found."}],["$","div",null,{"style":{"fontFamily":"system-ui,\"Segoe UI\",Roboto,Helvetica,Arial,sans-serif,\"Apple Color Emoji\",\"Segoe UI Emoji\"","height":"100vh","textAlign":"center","display":"flex","flexDirection":"column","alignItems":"center","justifyContent":"center"},"children":["$","div",null,{"children":[["$","style",null,{"dangerouslySetInnerHTML":{"__html":"body{color:#000;background:#fff;margin:0}.next-error-h1{border-right:1px solid rgba(0,0,0,.3)}@media (prefers-color-scheme:dark){body{color:#fff;background:#000}.next-error-h1{border-right:1px solid rgba(255,255,255,.3)}}"}}],["$","h1",null,{"className":"next-error-h1","style":{"display":"inline-block","margin":"0 20px 0 0","padding":"0 23px 0 0","fontSize":24,"fontWeight":500,"verticalAlign":"top","lineHeight":"49px"},"children":404}],["$","div",null,{"style":{"display":"inline-block"},"children":["$","h2",null,{"style":{"fontSize":14,"fontWeight":400,"lineHeight":"49px","margin":0},"children":"This page could not be found."}]}]]}]}]],[]]}]}]}]}]]}],"loading":null,"isPartial":false}
|
||||
:HL["/litellm-asset-prefix/_next/static/chunks/1ff47604985886e0.css","style"]
|
||||
0:{"buildId":"62sKsiTJhIKKiZmdKo1av","rsc":["$","$1","c",{"children":[[["$","link","0",{"rel":"stylesheet","href":"/litellm-asset-prefix/_next/static/chunks/4e20891f2fd03463.css","precedence":"next"}],["$","link","1",{"rel":"stylesheet","href":"/litellm-asset-prefix/_next/static/chunks/1ff47604985886e0.css","precedence":"next"}],["$","script","script-0",{"src":"/litellm-asset-prefix/_next/static/chunks/26adfa4e8ffc85c7.js","async":true}],["$","script","script-1",{"src":"/litellm-asset-prefix/_next/static/chunks/e8ed72789c2b42ff.js","async":true}]],["$","html",null,{"lang":"en","children":["$","body",null,{"className":"inter_5972bc34-module__OU16Qa__className","children":["$","$L2",null,{"children":["$","$L3",null,{"parallelRouterKey":"children","template":["$","$L4",null,{}],"notFound":[[["$","title",null,{"children":"404: This page could not be found."}],["$","div",null,{"style":{"fontFamily":"system-ui,\"Segoe UI\",Roboto,Helvetica,Arial,sans-serif,\"Apple Color Emoji\",\"Segoe UI Emoji\"","height":"100vh","textAlign":"center","display":"flex","flexDirection":"column","alignItems":"center","justifyContent":"center"},"children":["$","div",null,{"children":[["$","style",null,{"dangerouslySetInnerHTML":{"__html":"body{color:#000;background:#fff;margin:0}.next-error-h1{border-right:1px solid rgba(0,0,0,.3)}@media (prefers-color-scheme:dark){body{color:#fff;background:#000}.next-error-h1{border-right:1px solid rgba(255,255,255,.3)}}"}}],["$","h1",null,{"className":"next-error-h1","style":{"display":"inline-block","margin":"0 20px 0 0","padding":"0 23px 0 0","fontSize":24,"fontWeight":500,"verticalAlign":"top","lineHeight":"49px"},"children":404}],["$","div",null,{"style":{"display":"inline-block"},"children":["$","h2",null,{"style":{"fontSize":14,"fontWeight":400,"lineHeight":"49px","margin":0},"children":"This page could not be found."}]}]]}]}]],[]]}]}]}]}]]}],"loading":null,"isPartial":false}
|
||||
|
|
|
|||
|
|
@ -1,5 +1,5 @@
|
|||
:HL["/litellm-asset-prefix/_next/static/chunks/4e20891f2fd03463.css","style"]
|
||||
:HL["/litellm-asset-prefix/_next/static/chunks/a601549506e6d96f.css","style"]
|
||||
:HL["/litellm-asset-prefix/_next/static/chunks/1ff47604985886e0.css","style"]
|
||||
:HL["/litellm-asset-prefix/_next/static/media/83afe278b6a6bb3c-s.p.3a6ba036.woff2","font",{"crossOrigin":"","type":"font/woff2"}]
|
||||
:HL["/litellm-asset-prefix/_next/static/chunks/3f3fa56b5786d58c.css","style"]
|
||||
0:{"buildId":"w3I6ZteDnT32i9JBryDMD","tree":{"name":"","paramType":null,"paramKey":"","hasRuntimePrefetch":false,"slots":{"children":{"name":"__PAGE__","paramType":null,"paramKey":"__PAGE__","hasRuntimePrefetch":false,"slots":null,"isRootLayout":false}},"isRootLayout":true},"staleTime":300}
|
||||
0:{"buildId":"62sKsiTJhIKKiZmdKo1av","tree":{"name":"","paramType":null,"paramKey":"","hasRuntimePrefetch":false,"slots":{"children":{"name":"__PAGE__","paramType":null,"paramKey":"__PAGE__","hasRuntimePrefetch":false,"slots":null,"isRootLayout":false}},"isRootLayout":true},"staleTime":300}
|
||||
|
|
|
|||
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
|
|
@ -1 +0,0 @@
|
|||
(globalThis.TURBOPACK||(globalThis.TURBOPACK=[])).push(["object"==typeof document?document.currentScript:void 0,526612,e=>{"use strict";var t=e.i(843476),s=e.i(846835),i=e.i(135214),r=e.i(271645),o=e.i(702597);e.s(["default",0,()=>{let{userId:e,accessToken:u,userRole:a,premiumUser:n}=(0,i.default)(),[c,l]=(0,r.useState)([]),[f,d]=(0,r.useState)([]);return(0,r.useEffect)(()=>{(0,s.fetchOrganizations)(u,l).then(()=>{})},[u]),(0,r.useEffect)(()=>{(0,o.fetchUserModels)(e,a,u,d).then(()=>{})},[e,a,u]),(0,t.jsx)(s.default,{organizations:c,userRole:a,userModels:f,accessToken:u,setOrganizations:l,premiumUser:n})}])},601236,e=>{e.v(e=>Promise.resolve().then(()=>e(764205)))}]);
|
||||
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
|
|
@ -0,0 +1 @@
|
|||
(globalThis.TURBOPACK||(globalThis.TURBOPACK=[])).push(["object"==typeof document?document.currentScript:void 0,21548,e=>{"use strict";var t=e.i(616303);e.s(["Empty",()=>t.default])},601236,e=>{e.v(e=>Promise.resolve().then(()=>e(764205)))}]);
|
||||
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue