mirror of
https://github.com/BerriAI/litellm.git
synced 2026-10-10 03:28:53 +00:00
Merge branch 'main' into litellm_fix_responses_bridge_gpr-5.4
This commit is contained in:
 Sameer Kankute
GitHub
commit
6c3e036648
135 changed files with 4467 additions and 1383 deletions
|
|
@ -91,6 +91,10 @@ LiteLLM is a unified interface for 100+ LLM providers with two main components:
|
|||
- Async/await patterns throughout
|
||||
- Type hints required for all public APIs
|
||||
- **Avoid imports within methods** — place all imports at the top of the file (module-level). Inline imports inside functions/methods make dependencies harder to trace and hurt readability. The only exception is avoiding circular imports where absolutely necessary.
|
||||
- **Use dict spread for immutable copies** — prefer `{**original, "key": new_value}` over `dict(obj)` + mutation. The spread produces the final dict in one step and makes intent clear.
|
||||
- **Guard at resolution time** — when resolving an optional value through a fallback chain (`a or b or ""`), raise immediately if the resolved result being empty is an error. Don't pass empty strings or sentinel values downstream for the callee to deal with.
|
||||
- **Extract complex comprehensions to named helpers** — a set/dict comprehension that calls into the DB or manager (e.g. "which of these server IDs are OAuth2?") belongs in a named helper function, not inline in the caller.
|
||||
- **FastAPI parameter declarations** — mark required query/form params with `= Query(...)` / `= Form(...)` explicitly when other params in the same handler are optional. Mixing `str` (required) with `Optional[str] = None` in the same signature causes silent 422s when the required param is missing.
|
||||
|
||||
### Testing Strategy
|
||||
- Unit tests in `tests/test_litellm/`
|
||||
|
|
@ -98,6 +102,8 @@ LiteLLM is a unified interface for 100+ LLM providers with two main components:
|
|||
- Proxy tests in `tests/proxy_unit_tests/`
|
||||
- Load tests in `tests/load_tests/`
|
||||
- **Always add tests when adding new entity types or features** — if the existing test file covers other entity types, add corresponding tests for the new one
|
||||
- **Keep monkeypatch stubs in sync with real signatures** — when a function gains a new optional parameter, update every `fake_*` / `stub_*` in tests that patch it to also accept that kwarg (even as `**kwargs`). Stale stubs fail with `unexpected keyword argument` and mask real bugs.
|
||||
- **Test all branches of name→ID resolution** — when adding server/resource lookup that resolves names to UUIDs, test: (1) name resolves and UUID is allowed, (2) name resolves but UUID is not allowed, (3) name does not resolve at all. The silent-fallback path is where access-control bugs hide.
|
||||
|
||||
### UI / Backend Consistency
|
||||
- When wiring a new UI entity type to an existing backend endpoint, verify the backend API contract (single value vs. array, required vs. optional params) and ensure the UI controls match — e.g., use a single-select dropdown when the backend accepts a single value, not a multi-select
|
||||
|
|
|
|||
|
|
@ -49,7 +49,7 @@ USER root
|
|||
|
||||
# Install runtime dependencies (libsndfile needed for audio processing on ARM64)
|
||||
RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip libsndfile && \
|
||||
npm install -g npm@latest tar@7.5.10 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 && \
|
||||
npm install -g npm@latest tar@7.5.11 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 && \
|
||||
# SECURITY FIX: npm bundles tar, glob, and brace-expansion at multiple nested
|
||||
# levels inside its dependency tree. `npm install -g <pkg>` only creates a
|
||||
# SEPARATE global package, it does NOT replace npm's internal copies.
|
||||
|
|
|
|||
|
|
@ -19,7 +19,7 @@ RUN apt-get update && apt-get upgrade -y \
|
|||
libgnutls30 \
|
||||
libc6 && \
|
||||
apt-get install -y nodejs npm && \
|
||||
npm install -g npm@latest tar@7.5.10 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 && \
|
||||
npm install -g npm@latest tar@7.5.11 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 && \
|
||||
GLOBAL="$(npm root -g)" && \
|
||||
find "$GLOBAL/npm" -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
|
|
|
|||
|
|
@ -50,7 +50,7 @@ USER root
|
|||
|
||||
# Install runtime dependencies
|
||||
RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip libsndfile && \
|
||||
npm install -g npm@latest tar@7.5.10 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 && \
|
||||
npm install -g npm@latest tar@7.5.11 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 && \
|
||||
GLOBAL="$(npm root -g)" && \
|
||||
find "$GLOBAL/npm" -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
|
|
|
|||
|
|
@ -75,7 +75,7 @@ RUN apt-get update && apt-get upgrade -y \
|
|||
nodejs \
|
||||
npm \
|
||||
&& rm -rf /var/lib/apt/lists/* \
|
||||
&& npm install -g npm@latest tar@7.5.10 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 \
|
||||
&& npm install -g npm@latest tar@7.5.11 glob@11.1.0 @isaacs/brace-expansion@5.0.1 minimatch@10.2.4 diff@8.0.3 \
|
||||
&& GLOBAL="$(npm root -g)" \
|
||||
&& find "$GLOBAL/npm" -type d -name "tar" -path "*/node_modules/tar" | while read d; do \
|
||||
rm -rf "$d" && cp -rL "$GLOBAL/tar" "$d"; \
|
||||
|
|
|
|||
|
|
@ -935,6 +935,9 @@ router_settings:
|
|||
| PROXY_BASE_URL | Base URL for proxy service
|
||||
| PROXY_BATCH_WRITE_AT | Time in seconds to wait before batch writing spend logs to the database. Default is 10
|
||||
| PROXY_BATCH_POLLING_INTERVAL | Time in seconds to wait before polling a batch, to check if it's completed. Default is 6000s (1 hour)
|
||||
| PROXY_BATCH_POLLING_ENABLED | Set to `false` to disable the `CheckBatchCost` and `CheckResponsesCost` background polling jobs entirely. Useful for emergency mitigation on installs with large numbers of stale managed objects. Default is `true`
|
||||
| MAX_OBJECTS_PER_POLL_CYCLE | Maximum number of managed objects (batches / responses) fetched per polling cycle. Prevents OOM on installs with many stale rows. Default is `50`
|
||||
| MANAGED_OBJECT_STALENESS_CUTOFF_DAYS | Managed objects older than this many days in a non-terminal state are marked `stale_expired` at the start of each poll cycle and skipped. Default is `7`
|
||||
| PROXY_BUDGET_RESCHEDULER_MAX_TIME | Maximum time in seconds to wait before checking database for budget resets. Default is 605
|
||||
| PROXY_BUDGET_RESCHEDULER_MIN_TIME | Minimum time in seconds to wait before checking database for budget resets. Default is 597
|
||||
| PYTHON_GC_THRESHOLD | GC thresholds ('gen0,gen1,gen2', e.g. '1000,50,50'); defaults to Python’s values.
|
||||
|
|
|
|||
|
|
@ -177,3 +177,7 @@ Expect to see this metric on prometheus to track the Remaining Budget for the te
|
|||
```shell
|
||||
litellm_remaining_team_budget_metric{team_alias="QA Prod Bot",team_id="de35b29e-6ca8-4f47-b804-2b79d07aa99a"} 9.699999999999992e-06
|
||||
```
|
||||
|
||||
## See Also
|
||||
|
||||
- [Per-model TPM/RPM for teams](./users.md#per-team-model) - Set rate limits per model for all keys in a team
|
||||
|
|
|
|||
138
docs/my-website/docs/proxy/ui/ui_edit_logo.md
Normal file
138
docs/my-website/docs/proxy/ui/ui_edit_logo.md
Normal file
|
|
@ -0,0 +1,138 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Customize UI Logo
|
||||
|
||||
Personalize your LiteLLM dashboard by replacing the default logo with your own company branding. You can set a custom logo via the UI or the API.
|
||||
|
||||
## Via the UI
|
||||
|
||||
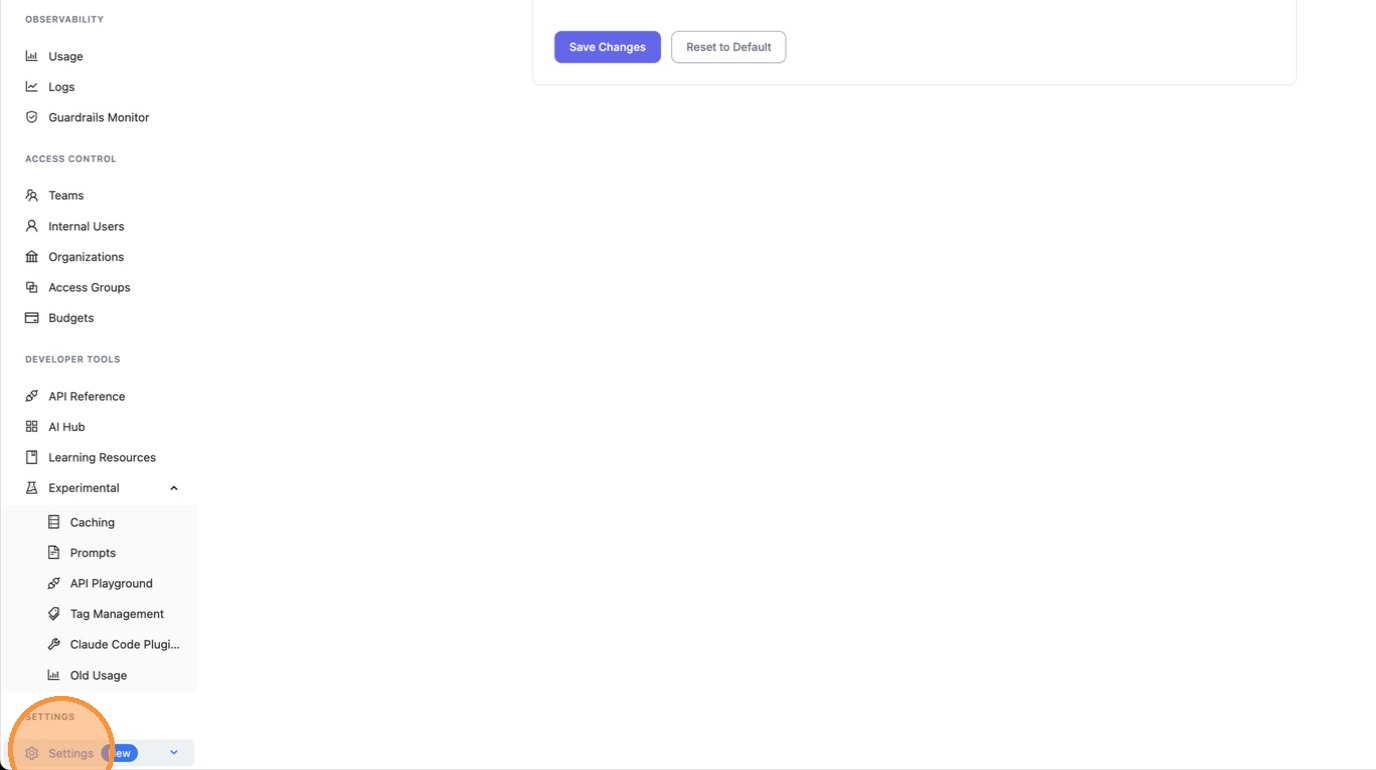
### 1. Navigate to Settings
|
||||
|
||||
Click the **Settings** icon in the sidebar.
|
||||
|
||||
|
||||
|
||||
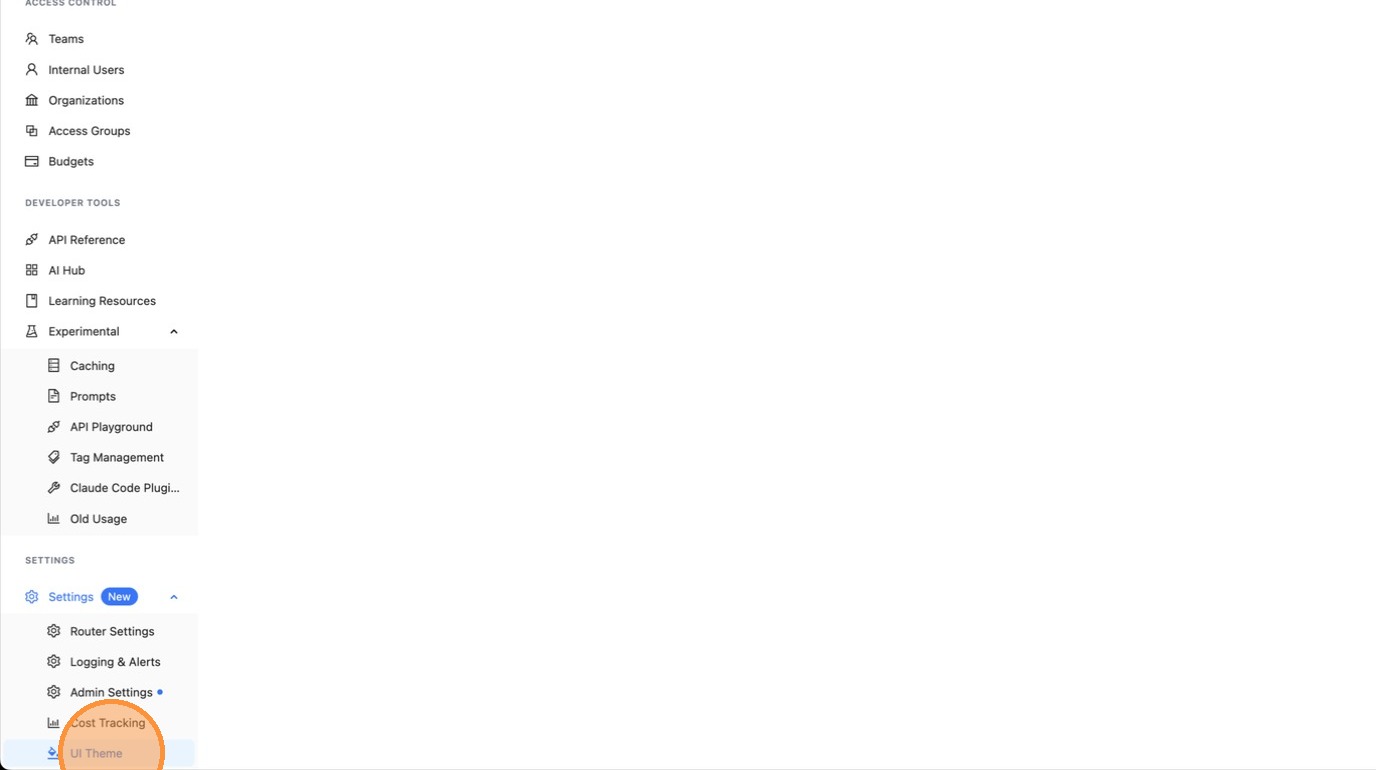
### 2. Open UI Theme Settings
|
||||
|
||||
Click **UI Theme** from the settings menu.
|
||||
|
||||
|
||||
|
||||
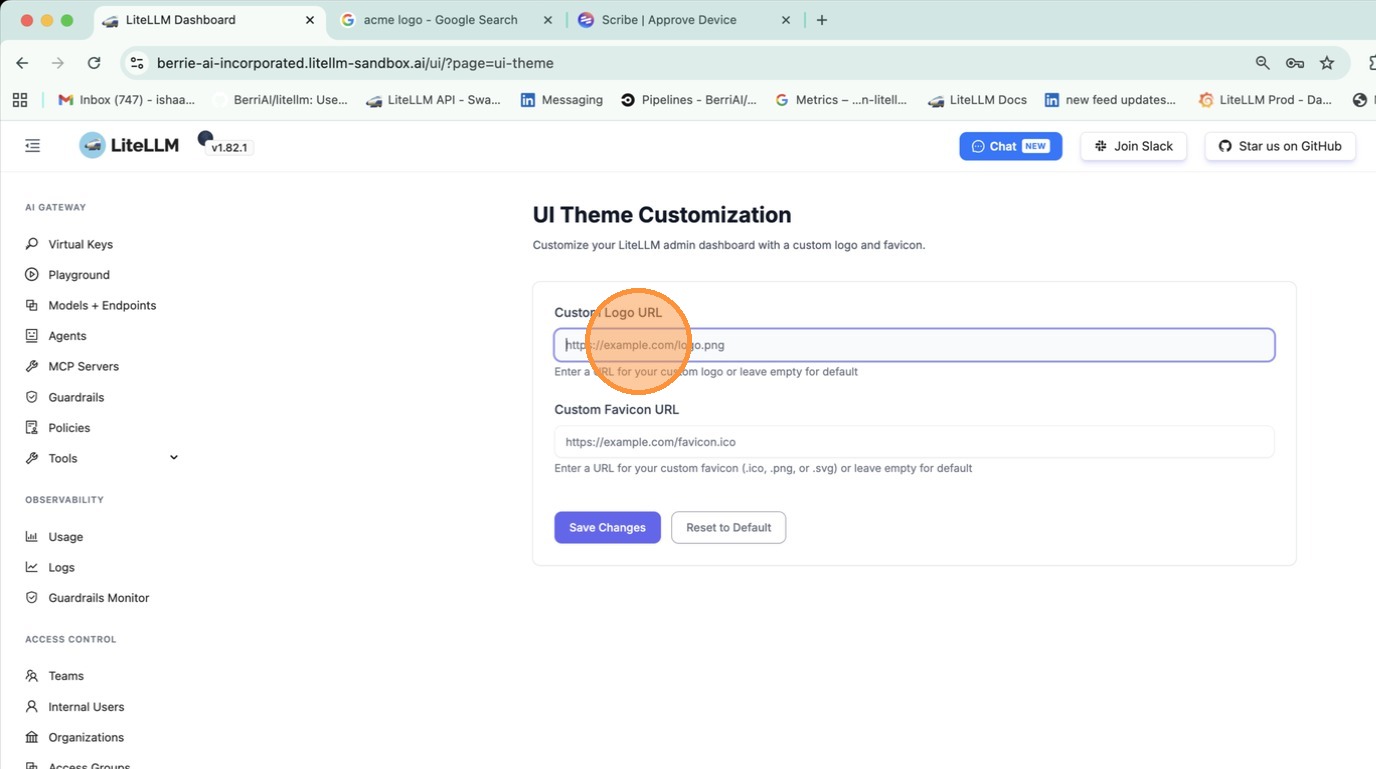
### 3. Click the Logo URL Field
|
||||
|
||||
Click the **Logo URL** text field to start editing.
|
||||
|
||||
|
||||
|
||||
### 4. Find Your Logo Image
|
||||
|
||||
Open a new browser tab and find the logo image you want to use (e.g., search Google Images for your company logo).
|
||||
|
||||

|
||||
|
||||
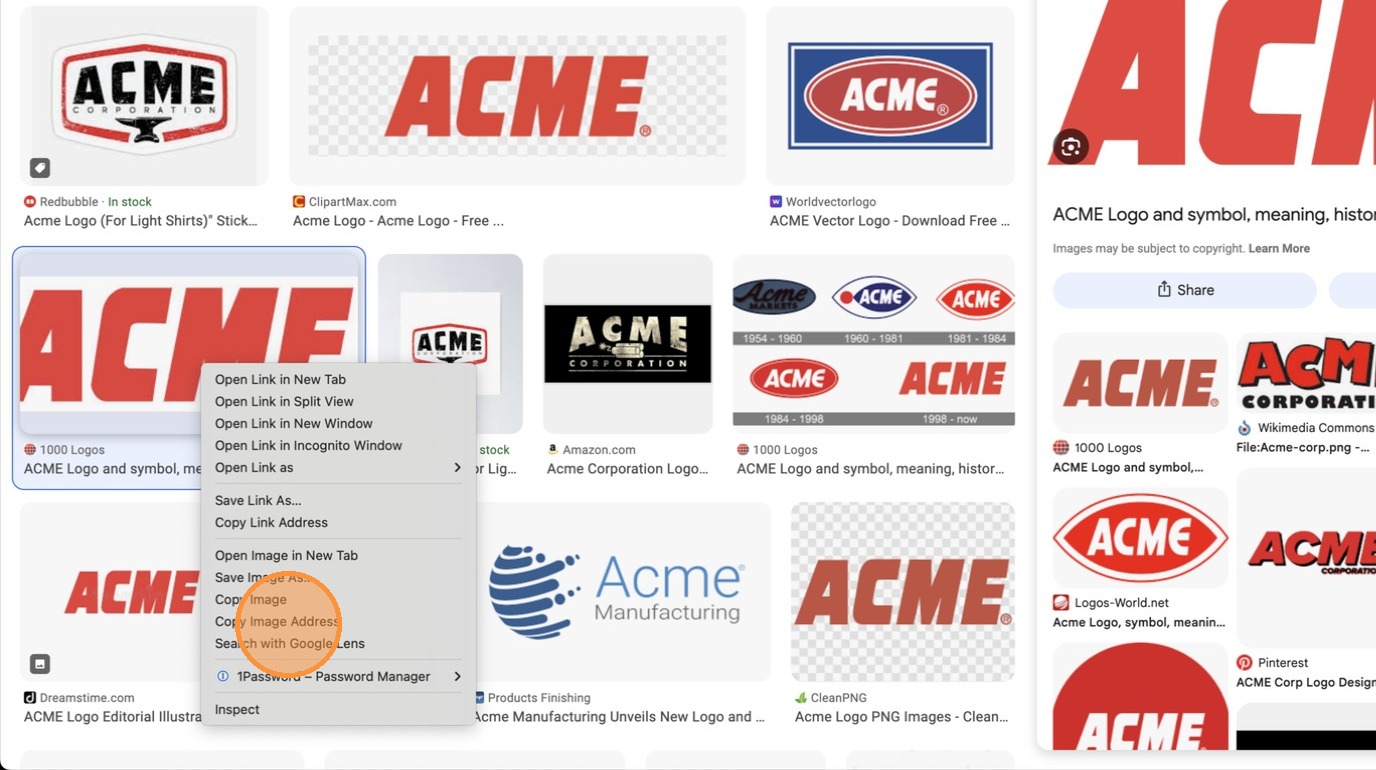
### 5. Right-Click on the Logo Image
|
||||
|
||||
Right-click the image you want to use as your logo.
|
||||
|
||||

|
||||
|
||||
### 6. Copy the Image Address
|
||||
|
||||
Select **Copy Image Address** from the context menu to copy the URL.
|
||||
|
||||
|
||||
|
||||
### 7. Switch Back to LiteLLM
|
||||
|
||||
Navigate back to the LiteLLM UI tab (e.g., press **Cmd + Left** or click the tab).
|
||||
|
||||
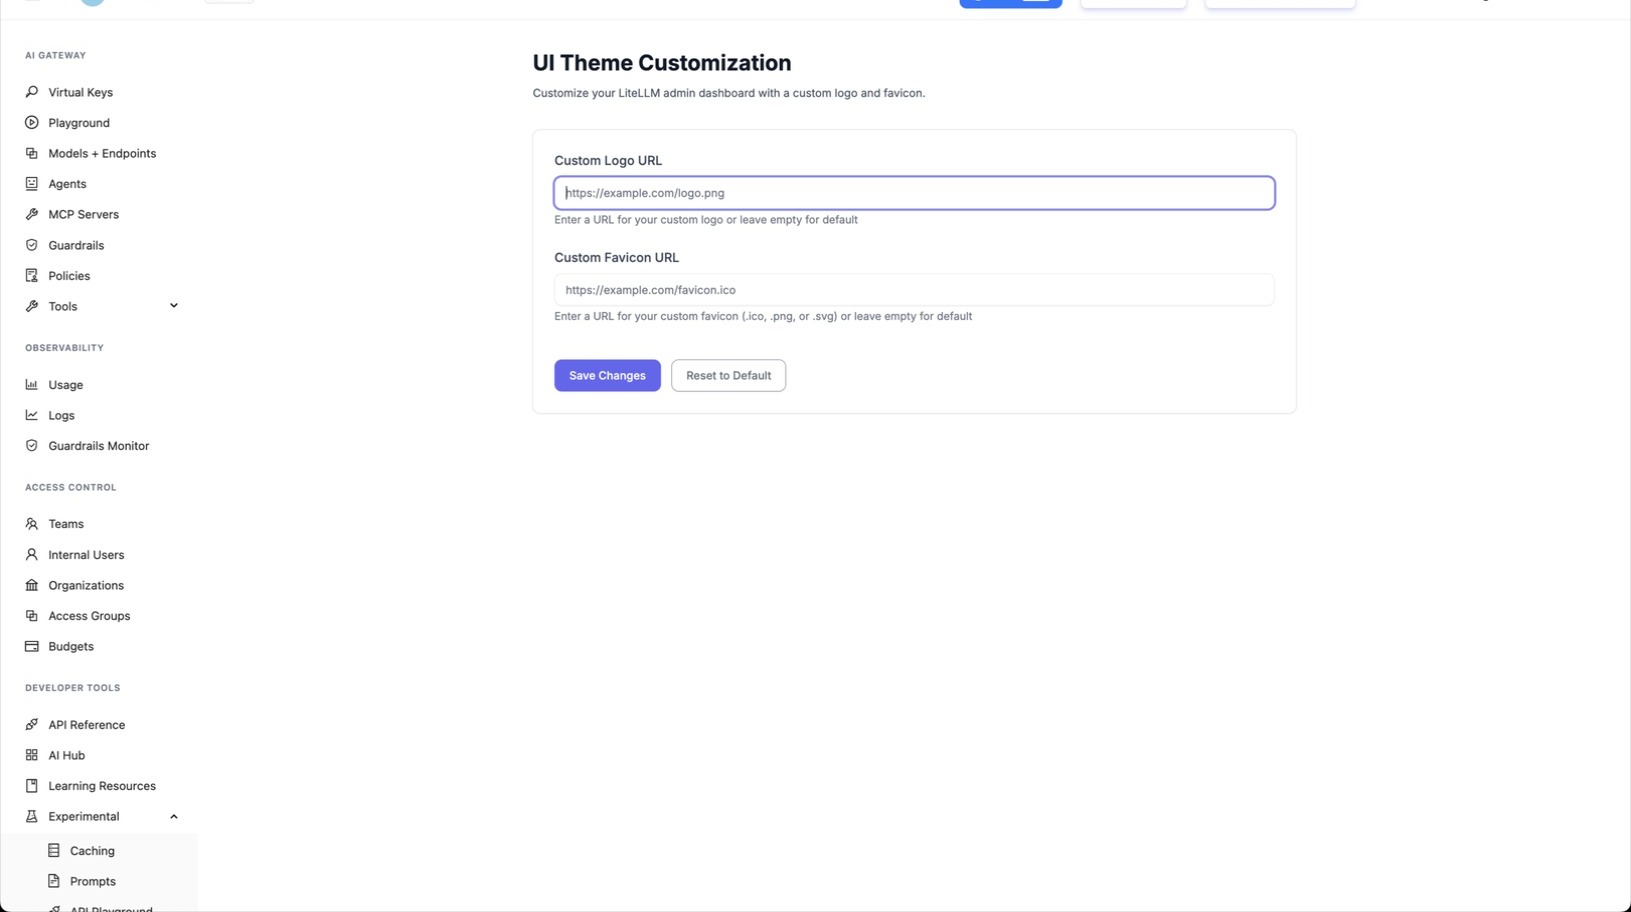
|
||||
|
||||
### 8. Paste the Logo URL
|
||||
|
||||
Paste the copied image URL into the **Logo URL** field with **Cmd + V**.
|
||||
|
||||
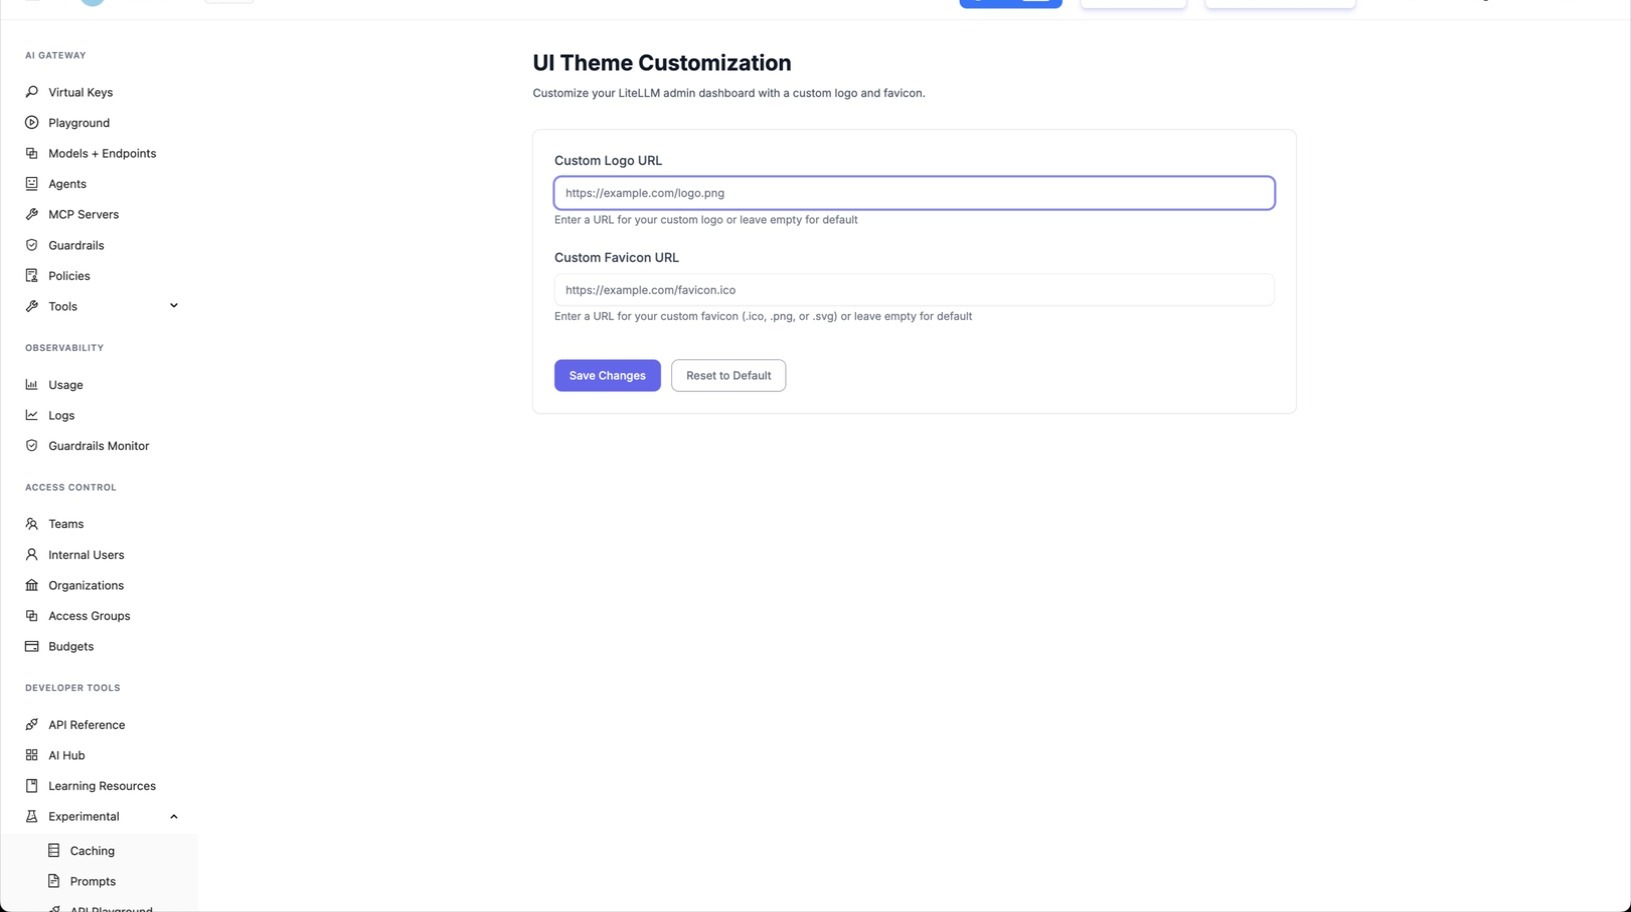
|
||||
|
||||
### 9. Save Changes
|
||||
|
||||
Click **Save Changes** to apply your new logo.
|
||||
|
||||
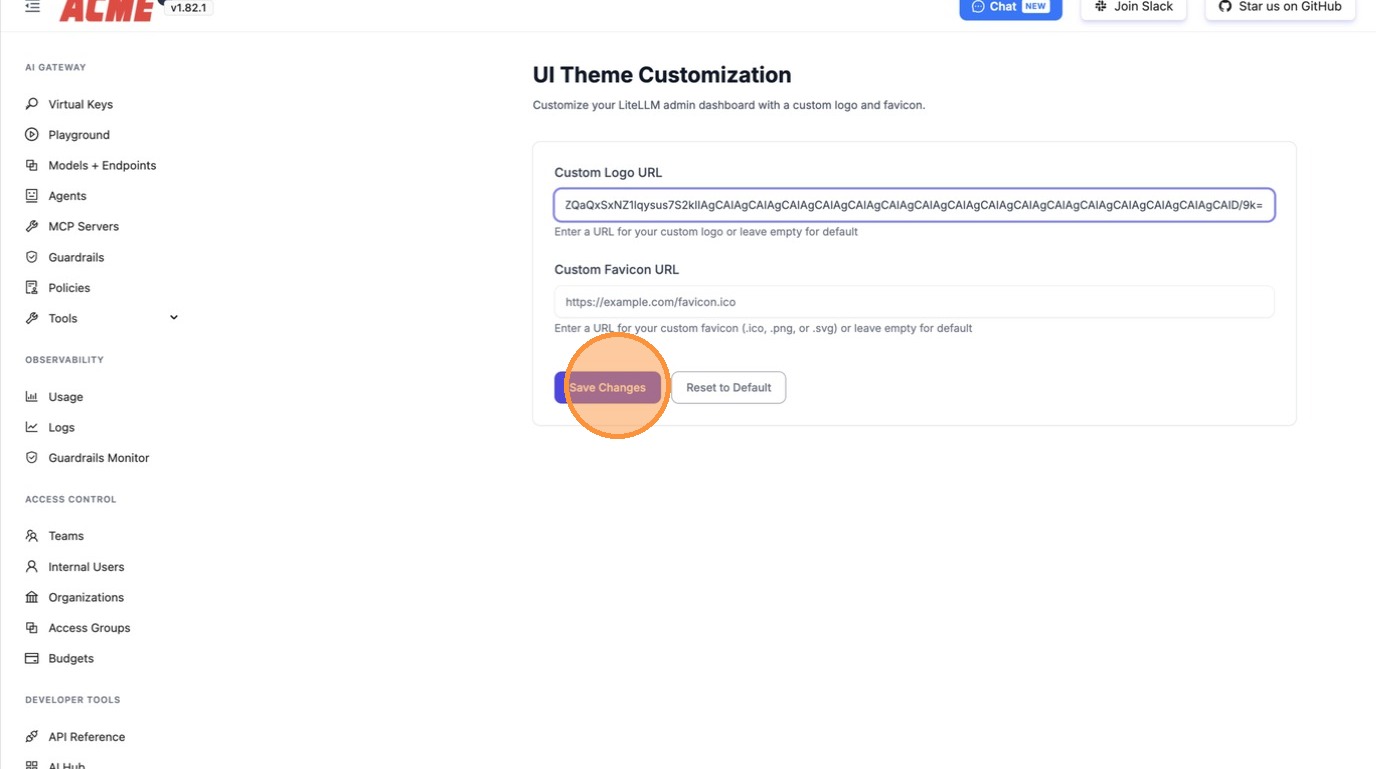
|
||||
|
||||
Your custom logo will now appear in the LiteLLM dashboard sidebar and login page.
|
||||
|
||||
## Via the API
|
||||
|
||||
### Set a Custom Logo
|
||||
|
||||
```bash
|
||||
curl -X PATCH 'http://localhost:4000/settings/update/ui_theme_settings' \
|
||||
-H 'Authorization: Bearer <your-admin-key>' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-d '{
|
||||
"logo_url": "https://example.com/your-company-logo.png"
|
||||
}'
|
||||
```
|
||||
|
||||
### Set a Custom Favicon
|
||||
|
||||
You can also customize the browser tab favicon:
|
||||
|
||||
```bash
|
||||
curl -X PATCH 'http://localhost:4000/settings/update/ui_theme_settings' \
|
||||
-H 'Authorization: Bearer <your-admin-key>' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-d '{
|
||||
"logo_url": "https://example.com/your-company-logo.png",
|
||||
"favicon_url": "https://example.com/your-favicon.ico"
|
||||
}'
|
||||
```
|
||||
|
||||
### Get Current Theme Settings
|
||||
|
||||
```bash
|
||||
curl -X GET 'http://localhost:4000/settings/get/ui_theme_settings'
|
||||
```
|
||||
|
||||
### Reset to Default Logo
|
||||
|
||||
Send an empty `logo_url` to restore the default LiteLLM logo:
|
||||
|
||||
```bash
|
||||
curl -X PATCH 'http://localhost:4000/settings/update/ui_theme_settings' \
|
||||
-H 'Authorization: Bearer <your-admin-key>' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-d '{
|
||||
"logo_url": ""
|
||||
}'
|
||||
```
|
||||
|
||||
## Via `proxy_config.yaml`
|
||||
|
||||
You can also set the logo URL in your proxy configuration file:
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
ui_theme_config:
|
||||
logo_url: "https://example.com/your-company-logo.png"
|
||||
favicon_url: "https://example.com/your-favicon.ico" # optional
|
||||
```
|
||||
|
||||
Or set it as an environment variable:
|
||||
|
||||
```yaml
|
||||
environment_variables:
|
||||
UI_LOGO_PATH: "https://example.com/your-company-logo.png"
|
||||
```
|
||||
|
||||
## Supported Logo Formats
|
||||
|
||||
| Format | Supported |
|
||||
|--------|-----------|
|
||||
| JPEG / JPG | Yes |
|
||||
| PNG | Yes |
|
||||
| SVG | Yes |
|
||||
| ICO (favicon only) | Yes |
|
||||
| HTTP/HTTPS URL | Yes |
|
||||
| Local file path | Yes |
|
||||
|
|
@ -641,7 +641,7 @@ You can set:
|
|||
- tpm limits (tokens per minute)
|
||||
- rpm limits (requests per minute)
|
||||
- max parallel requests
|
||||
- rpm / tpm limits per model for a given key
|
||||
- rpm / tpm limits per model for a given key or team
|
||||
|
||||
### TPM Rate Limit Type (Input/Output/Total)
|
||||
|
||||
|
|
@ -689,6 +689,62 @@ curl --location 'http://0.0.0.0:4000/team/new' \
|
|||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="per-team-model" label="Per Team Per Model">
|
||||
|
||||
**Set rate limits per model for a team**
|
||||
|
||||
Use `model_rpm_limit` and `model_tpm_limit` to set rate limits per model for all keys belonging to a team. These limits apply across all keys in the team and are inherited by keys unless overridden at the key level.
|
||||
|
||||
Use `/team/new` or `/team/update` with `model_rpm_limit` and `model_tpm_limit` as dictionaries mapping model names to their limits:
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/team/new' \
|
||||
--header 'Authorization: Bearer sk-1234' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"team_id": "my-prod-team",
|
||||
"model_rpm_limit": {"gpt-4": 100, "gpt-3.5-turbo": 200},
|
||||
"model_tpm_limit": {"gpt-4": 10000, "gpt-3.5-turbo": 20000}
|
||||
}'
|
||||
```
|
||||
|
||||
**Update existing team with per-model limits:**
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/team/update' \
|
||||
--header 'Authorization: Bearer sk-1234' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"team_id": "my-prod-team",
|
||||
"model_rpm_limit": {"gpt-4": 100, "gpt-3.5-turbo": 200},
|
||||
"model_tpm_limit": {"gpt-4": 10000, "gpt-3.5-turbo": 20000}
|
||||
}'
|
||||
```
|
||||
|
||||
**Alternative: Use metadata**
|
||||
|
||||
You can also pass per-model limits via the `metadata` field:
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/team/update' \
|
||||
--header 'Authorization: Bearer sk-1234' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"team_id": "my-prod-team",
|
||||
"metadata": {
|
||||
"model_rpm_limit": {"gpt-4": 100, "gpt-3.5-turbo": 200},
|
||||
"model_tpm_limit": {"gpt-4": 10000, "gpt-3.5-turbo": 20000}
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
**Resolution order:** When a key belongs to a team, rate limits are resolved as: **Key metadata > Key model_max_budget > Team metadata**. Keys can override team-level per-model limits with their own `model_rpm_limit` or `model_tpm_limit`.
|
||||
|
||||
**Verify:** Make a `/chat/completions` request and check response headers `x-litellm-key-remaining-requests-{model}` and `x-litellm-key-remaining-tokens-{model}` for the model-specific limits.
|
||||
|
||||
[**See Swagger**](https://litellm-api.up.railway.app/#/team%20management/new_team_team_new_post)
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="per-user" label="Per Internal User">
|
||||
|
||||
|
|
|
|||
|
|
@ -332,6 +332,7 @@ const sidebars = {
|
|||
label: "Setup & SSO",
|
||||
items: [
|
||||
"proxy/admin_ui_sso",
|
||||
"proxy/ui/ui_edit_logo",
|
||||
"proxy/custom_sso",
|
||||
"proxy/custom_root_ui",
|
||||
"tutorials/scim_litellm",
|
||||
|
|
|
|||
|
|
@ -2,11 +2,15 @@
|
|||
Polls LiteLLM_ManagedObjectTable to check if the batch job is complete, and if the cost has been tracked.
|
||||
"""
|
||||
|
||||
from litellm._uuid import uuid
|
||||
from datetime import datetime
|
||||
from datetime import datetime, timedelta, timezone
|
||||
from typing import TYPE_CHECKING, Optional
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm._uuid import uuid
|
||||
from litellm.constants import (
|
||||
MANAGED_OBJECT_STALENESS_CUTOFF_DAYS,
|
||||
MAX_OBJECTS_PER_POLL_CYCLE,
|
||||
)
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from litellm.proxy.utils import PrismaClient, ProxyLogging
|
||||
|
|
@ -29,6 +33,9 @@ class CheckBatchCost:
|
|||
self.proxy_logging_obj: ProxyLogging = proxy_logging_obj
|
||||
self.prisma_client: PrismaClient = prisma_client
|
||||
self.llm_router: Router = llm_router
|
||||
# Cached after the first poll cycle. Once we know the column is absent we skip
|
||||
# the guaranteed-failing primary query on every subsequent cycle.
|
||||
self._has_batch_processed_column: bool = True
|
||||
|
||||
async def _get_user_info(self, batch_id, user_id) -> dict:
|
||||
"""
|
||||
|
|
@ -49,6 +56,47 @@ class CheckBatchCost:
|
|||
verbose_proxy_logger.error(f"CheckBatchCost: could not look up user {user_id} for batch {batch_id}: {e}")
|
||||
return {}
|
||||
|
||||
async def _cleanup_stale_managed_objects(self) -> None:
|
||||
"""
|
||||
Mark managed objects older than MANAGED_OBJECT_STALENESS_CUTOFF_DAYS days
|
||||
in non-terminal states as 'stale_expired'. These will never complete and
|
||||
should not be polled.
|
||||
"""
|
||||
cutoff = datetime.now(timezone.utc) - timedelta(days=MANAGED_OBJECT_STALENESS_CUTOFF_DAYS)
|
||||
result = await self.prisma_client.db.litellm_managedobjecttable.update_many(
|
||||
where={
|
||||
"file_purpose": "batch",
|
||||
"status": {"not_in": ["completed", "complete", "failed", "expired", "cancelled", "stale_expired"]},
|
||||
"created_at": {"lt": cutoff},
|
||||
},
|
||||
data={"status": "stale_expired"},
|
||||
)
|
||||
if result > 0:
|
||||
verbose_proxy_logger.warning(
|
||||
f"CheckBatchCost: marked {result} stale managed objects "
|
||||
f"(older than {MANAGED_OBJECT_STALENESS_CUTOFF_DAYS} days) as stale_expired"
|
||||
)
|
||||
|
||||
async def _fallback_find_jobs(self) -> list:
|
||||
"""Query batch jobs without the batch_processed filter (for older schemas)."""
|
||||
return await self.prisma_client.db.litellm_managedobjecttable.find_many(
|
||||
where={
|
||||
"file_purpose": "batch",
|
||||
"status": {
|
||||
"not_in": [
|
||||
"failed",
|
||||
"expired",
|
||||
"cancelled",
|
||||
"complete",
|
||||
"completed",
|
||||
"stale_expired",
|
||||
]
|
||||
},
|
||||
},
|
||||
take=MAX_OBJECTS_PER_POLL_CYCLE,
|
||||
order={"created_at": "asc"},
|
||||
)
|
||||
|
||||
async def check_batch_cost(self):
|
||||
"""
|
||||
Check if the batch JOB has been tracked.
|
||||
|
|
@ -70,14 +118,48 @@ class CheckBatchCost:
|
|||
get_model_id_from_unified_batch_id,
|
||||
)
|
||||
|
||||
# Look for all batches that have not yet been processed by CheckBatchCost
|
||||
jobs = await self.prisma_client.db.litellm_managedobjecttable.find_many(
|
||||
where={
|
||||
"file_purpose": "batch",
|
||||
"batch_processed" : False,
|
||||
"status": {"not_in": ["failed", "expired", "cancelled"]}
|
||||
}
|
||||
)
|
||||
try:
|
||||
await self._cleanup_stale_managed_objects()
|
||||
except Exception as cleanup_err:
|
||||
verbose_proxy_logger.warning(
|
||||
f"CheckBatchCost: stale cleanup failed (poll will continue): {cleanup_err}"
|
||||
)
|
||||
|
||||
# Look for all batches that have not yet been processed by CheckBatchCost.
|
||||
# self._has_batch_processed_column is cached after the first probe so that
|
||||
# older schemas don't pay a guaranteed-failing primary query + warning on
|
||||
# every subsequent poll cycle.
|
||||
if self._has_batch_processed_column:
|
||||
try:
|
||||
jobs = await self.prisma_client.db.litellm_managedobjecttable.find_many(
|
||||
where={
|
||||
"file_purpose": "batch",
|
||||
"batch_processed": False,
|
||||
"status": {
|
||||
"not_in": [
|
||||
"failed",
|
||||
"expired",
|
||||
"cancelled",
|
||||
"complete",
|
||||
"completed",
|
||||
"stale_expired",
|
||||
]
|
||||
},
|
||||
},
|
||||
take=MAX_OBJECTS_PER_POLL_CYCLE,
|
||||
order={"created_at": "asc"},
|
||||
)
|
||||
except Exception as query_err:
|
||||
if "batch_processed" not in str(query_err).lower() and "unknown column" not in str(query_err).lower() and "does not exist" not in str(query_err).lower():
|
||||
raise
|
||||
# Permanent schema gap — cache the result so future cycles skip straight to fallback
|
||||
self._has_batch_processed_column = False
|
||||
verbose_proxy_logger.warning(
|
||||
"CheckBatchCost: batch_processed column not found, querying without it"
|
||||
)
|
||||
jobs = await self._fallback_find_jobs()
|
||||
else:
|
||||
jobs = await self._fallback_find_jobs()
|
||||
for job in jobs:
|
||||
# get the model from the job
|
||||
unified_object_id = job.unified_object_id
|
||||
|
|
@ -163,14 +245,14 @@ class CheckBatchCost:
|
|||
|
||||
# Access content - handle both direct attribute and method call
|
||||
if hasattr(_file_content, 'content'):
|
||||
content_bytes = _file_content.content
|
||||
content_bytes = _file_content.content # type: ignore[union-attr]
|
||||
elif hasattr(_file_content, 'read'):
|
||||
content_bytes = await _file_content.read()
|
||||
content_bytes = await _file_content.read() # type: ignore[misc]
|
||||
else:
|
||||
content_bytes = _file_content
|
||||
content_bytes = _file_content # type: ignore[assignment]
|
||||
|
||||
file_content_as_dict = _get_file_content_as_dictionary(
|
||||
content_bytes
|
||||
content_bytes # type: ignore[arg-type]
|
||||
)
|
||||
|
||||
deployment_info = self.llm_router.get_deployment(model_id=model_id)
|
||||
|
|
@ -195,7 +277,7 @@ class CheckBatchCost:
|
|||
file_content_dictionary=file_content_as_dict,
|
||||
custom_llm_provider=llm_provider, # type: ignore
|
||||
model_name=model_name,
|
||||
model_info=deployment_model_info,
|
||||
model_info=deployment_model_info, # type: ignore[arg-type]
|
||||
)
|
||||
)
|
||||
logging_obj = LiteLLMLogging(
|
||||
|
|
@ -236,13 +318,15 @@ class CheckBatchCost:
|
|||
|
||||
# mark the job as complete
|
||||
try:
|
||||
update_data: dict = {
|
||||
"status": "complete",
|
||||
"file_object": response.model_dump_json(),
|
||||
}
|
||||
if self._has_batch_processed_column:
|
||||
update_data["batch_processed"] = True
|
||||
await self.prisma_client.db.litellm_managedobjecttable.update(
|
||||
where={"id": job.id},
|
||||
data={
|
||||
"batch_processed": True,
|
||||
"status": "complete",
|
||||
"file_object": response.model_dump_json(),
|
||||
},
|
||||
data=update_data,
|
||||
)
|
||||
except Exception as db_err:
|
||||
verbose_proxy_logger.error(
|
||||
|
|
|
|||
|
|
@ -3,10 +3,15 @@ Polls LiteLLM_ManagedObjectTable to check if the response is complete.
|
|||
Cost tracking is handled automatically by litellm.aget_responses().
|
||||
"""
|
||||
|
||||
from datetime import datetime, timedelta, timezone
|
||||
from typing import TYPE_CHECKING
|
||||
|
||||
import litellm
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.constants import (
|
||||
MANAGED_OBJECT_STALENESS_CUTOFF_DAYS,
|
||||
MAX_OBJECTS_PER_POLL_CYCLE,
|
||||
)
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from litellm.proxy.utils import PrismaClient, ProxyLogging
|
||||
|
|
@ -27,6 +32,27 @@ class CheckResponsesCost:
|
|||
self.prisma_client: PrismaClient = prisma_client
|
||||
self.llm_router: Router = llm_router
|
||||
|
||||
async def _cleanup_stale_managed_objects(self) -> None:
|
||||
"""
|
||||
Mark managed objects older than MANAGED_OBJECT_STALENESS_CUTOFF_DAYS days
|
||||
in non-terminal states as 'stale_expired'. These will never complete and
|
||||
should not be polled.
|
||||
"""
|
||||
cutoff = datetime.now(timezone.utc) - timedelta(days=MANAGED_OBJECT_STALENESS_CUTOFF_DAYS)
|
||||
result = await self.prisma_client.db.litellm_managedobjecttable.update_many(
|
||||
where={
|
||||
"file_purpose": "response",
|
||||
"status": {"not_in": ["completed", "complete", "failed", "expired", "cancelled", "stale_expired"]},
|
||||
"created_at": {"lt": cutoff},
|
||||
},
|
||||
data={"status": "stale_expired"},
|
||||
)
|
||||
if result > 0:
|
||||
verbose_proxy_logger.warning(
|
||||
f"CheckResponsesCost: marked {result} stale managed objects "
|
||||
f"(older than {MANAGED_OBJECT_STALENESS_CUTOFF_DAYS} days) as stale_expired"
|
||||
)
|
||||
|
||||
async def check_responses_cost(self):
|
||||
"""
|
||||
Check if background responses are complete and track their cost.
|
||||
|
|
@ -35,11 +61,20 @@ class CheckResponsesCost:
|
|||
- Cost is automatically tracked by litellm.aget_responses()
|
||||
- Mark completed/failed/cancelled responses as complete in the database
|
||||
"""
|
||||
try:
|
||||
await self._cleanup_stale_managed_objects()
|
||||
except Exception as cleanup_err:
|
||||
verbose_proxy_logger.warning(
|
||||
f"CheckResponsesCost: stale cleanup failed (poll will continue): {cleanup_err}"
|
||||
)
|
||||
|
||||
jobs = await self.prisma_client.db.litellm_managedobjecttable.find_many(
|
||||
where={
|
||||
"status": {"in": ["queued", "in_progress"]},
|
||||
"file_purpose": "response",
|
||||
}
|
||||
},
|
||||
take=MAX_OBJECTS_PER_POLL_CYCLE,
|
||||
order={"created_at": "asc"},
|
||||
)
|
||||
|
||||
verbose_proxy_logger.debug(f"Found {len(jobs)} response jobs to check")
|
||||
|
|
|
|||
|
|
@ -1897,7 +1897,7 @@ if TYPE_CHECKING:
|
|||
supports_reasoning: Callable[..., bool]
|
||||
acreate: Callable[..., Any]
|
||||
get_max_tokens: Callable[..., int]
|
||||
get_model_info: Callable[..., _ModelInfoType]
|
||||
get_model_info: Callable[..., _ModelInfoType] # type: ignore[no-redef]
|
||||
register_prompt_template: Callable[..., None]
|
||||
validate_environment: Callable[..., dict]
|
||||
check_valid_key: Callable[..., bool]
|
||||
|
|
|
|||
|
|
@ -398,9 +398,12 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
ResponseOutputMessage,
|
||||
ResponseReasoningItem,
|
||||
)
|
||||
from openai.types.responses.response_output_item import (
|
||||
ResponseApplyPatchToolCall,
|
||||
)
|
||||
try:
|
||||
from openai.types.responses.response_output_item import (
|
||||
ResponseApplyPatchToolCall,
|
||||
)
|
||||
except ImportError:
|
||||
ResponseApplyPatchToolCall = None # type: ignore[assignment,misc]
|
||||
|
||||
from litellm.types.utils import Choices, Message
|
||||
|
||||
|
|
@ -457,7 +460,7 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
accumulated_tool_calls.append(tool_call_dict)
|
||||
tool_call_index += 1
|
||||
|
||||
elif isinstance(item, ResponseApplyPatchToolCall):
|
||||
elif ResponseApplyPatchToolCall is not None and isinstance(item, ResponseApplyPatchToolCall):
|
||||
from litellm.responses.litellm_completion_transformation.transformation import (
|
||||
LiteLLMCompletionResponsesConfig,
|
||||
)
|
||||
|
|
|
|||
|
|
@ -1351,6 +1351,15 @@ PROXY_BUDGET_RESCHEDULER_MIN_TIME = int(
|
|||
os.getenv("PROXY_BUDGET_RESCHEDULER_MIN_TIME", 597)
|
||||
)
|
||||
PROXY_BATCH_POLLING_INTERVAL = int(os.getenv("PROXY_BATCH_POLLING_INTERVAL", 3600))
|
||||
MAX_OBJECTS_PER_POLL_CYCLE = max(1, int(os.getenv("MAX_OBJECTS_PER_POLL_CYCLE", 50)))
|
||||
MANAGED_OBJECT_STALENESS_CUTOFF_DAYS = max(
|
||||
1, int(os.getenv("MANAGED_OBJECT_STALENESS_CUTOFF_DAYS", 7))
|
||||
)
|
||||
# Set PROXY_BATCH_POLLING_ENABLED=false to disable the CheckBatchCost and
|
||||
# CheckResponsesCost background polling jobs entirely (e.g. to avoid DB load on
|
||||
# installations with large numbers of stale managed objects).
|
||||
_batch_polling_env = os.getenv("PROXY_BATCH_POLLING_ENABLED", "true").lower()
|
||||
PROXY_BATCH_POLLING_ENABLED = _batch_polling_env == "true"
|
||||
PROXY_BUDGET_RESCHEDULER_MAX_TIME = int(
|
||||
os.getenv("PROXY_BUDGET_RESCHEDULER_MAX_TIME", 605)
|
||||
)
|
||||
|
|
|
|||
|
|
@ -39,15 +39,6 @@ base_llm_http_handler = BaseLLMHTTPHandler()
|
|||
#################################################
|
||||
|
||||
|
||||
def _get_tool_config_from_kwargs(kwargs: Dict[str, Any]) -> Optional[Dict[str, Any]]:
|
||||
"""Read toolConfig/tool_config without dropping intentionally empty dicts."""
|
||||
if "toolConfig" in kwargs:
|
||||
return kwargs["toolConfig"]
|
||||
if "tool_config" in kwargs:
|
||||
return kwargs["tool_config"]
|
||||
return None
|
||||
|
||||
|
||||
class GenerateContentSetupResult(BaseModel):
|
||||
"""Internal Type - Result of setting up a generate content call"""
|
||||
|
||||
|
|
@ -180,14 +171,12 @@ class GenerateContentHelper:
|
|||
system_instruction = kwargs.get("systemInstruction") or kwargs.get(
|
||||
"system_instruction"
|
||||
)
|
||||
tool_config = _get_tool_config_from_kwargs(kwargs)
|
||||
request_body = (
|
||||
generate_content_provider_config.transform_generate_content_request(
|
||||
model=model,
|
||||
contents=contents,
|
||||
tools=tools,
|
||||
generate_content_config_dict=generate_content_config_dict,
|
||||
tool_config=tool_config,
|
||||
system_instruction=system_instruction,
|
||||
)
|
||||
)
|
||||
|
|
@ -334,7 +323,6 @@ def generate_content(
|
|||
system_instruction = kwargs.get("systemInstruction") or kwargs.get(
|
||||
"system_instruction"
|
||||
)
|
||||
tool_config = _get_tool_config_from_kwargs(kwargs)
|
||||
|
||||
# Check if we should use the adapter (when provider config is None)
|
||||
if setup_result.generate_content_provider_config is None:
|
||||
|
|
@ -366,7 +354,6 @@ def generate_content(
|
|||
_is_async=_is_async,
|
||||
client=kwargs.get("client"),
|
||||
litellm_metadata=kwargs.get("litellm_metadata", {}),
|
||||
tool_config=tool_config,
|
||||
system_instruction=system_instruction,
|
||||
)
|
||||
|
||||
|
|
@ -427,7 +414,6 @@ async def agenerate_content_stream(
|
|||
system_instruction = kwargs.get("systemInstruction") or kwargs.get(
|
||||
"system_instruction"
|
||||
)
|
||||
tool_config = _get_tool_config_from_kwargs(kwargs)
|
||||
|
||||
# Check if we should use the adapter (when provider config is None)
|
||||
if setup_result.generate_content_provider_config is None:
|
||||
|
|
@ -466,7 +452,6 @@ async def agenerate_content_stream(
|
|||
client=kwargs.get("client"),
|
||||
stream=True,
|
||||
litellm_metadata=kwargs.get("litellm_metadata", {}),
|
||||
tool_config=tool_config,
|
||||
system_instruction=system_instruction,
|
||||
)
|
||||
|
||||
|
|
@ -535,10 +520,6 @@ def generate_content_stream(
|
|||
)
|
||||
|
||||
# Call the handler with streaming enabled (sync version)
|
||||
system_instruction = kwargs.get("systemInstruction") or kwargs.get(
|
||||
"system_instruction"
|
||||
)
|
||||
tool_config = _get_tool_config_from_kwargs(kwargs)
|
||||
return base_llm_http_handler.generate_content_handler(
|
||||
model=setup_result.model,
|
||||
contents=contents,
|
||||
|
|
@ -555,8 +536,6 @@ def generate_content_stream(
|
|||
client=kwargs.get("client"),
|
||||
stream=True,
|
||||
litellm_metadata=kwargs.get("litellm_metadata", {}),
|
||||
tool_config=tool_config,
|
||||
system_instruction=system_instruction,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
|
|
|
|||
|
|
@ -2283,7 +2283,7 @@ def sanitize_messages_for_tool_calling(
|
|||
for idx, msg in enumerate(sanitized_messages):
|
||||
role = msg.get("role")
|
||||
tcid = msg.get("tool_call_id") if role in ["tool", "function"] else None
|
||||
if tcid:
|
||||
if tcid and isinstance(tcid, str):
|
||||
if tcid in seen_in_block:
|
||||
# Mark the earlier occurrence for removal (keep latest)
|
||||
duplicates_to_remove.add(seen_in_block[tcid])
|
||||
|
|
@ -2581,13 +2581,11 @@ def anthropic_messages_pt( # noqa: PLR0915
|
|||
|
||||
# Build the text block if content is a non-empty string
|
||||
text_element = None
|
||||
if (
|
||||
isinstance(assistant_content_block.get("content"), str)
|
||||
and assistant_content_block["content"]
|
||||
):
|
||||
_acb_content = assistant_content_block.get("content")
|
||||
if isinstance(_acb_content, str) and _acb_content:
|
||||
_anthropic_text_content_element = AnthropicMessagesTextParam(
|
||||
type="text",
|
||||
text=assistant_content_block["content"],
|
||||
text=_acb_content,
|
||||
)
|
||||
_content_element = add_cache_control_to_content(
|
||||
anthropic_content_element=_anthropic_text_content_element,
|
||||
|
|
@ -2682,9 +2680,10 @@ def anthropic_messages_pt( # noqa: PLR0915
|
|||
_content_is_list = "content" in assistant_content_block and isinstance(
|
||||
assistant_content_block["content"], list
|
||||
)
|
||||
_content_list = assistant_content_block.get("content") if _content_is_list else None
|
||||
_list_has_thinking = False
|
||||
if _content_is_list:
|
||||
for _item in assistant_content_block["content"]:
|
||||
if _content_is_list and _content_list is not None:
|
||||
for _item in _content_list:
|
||||
if isinstance(_item, dict) and _item.get("type") in (
|
||||
"thinking",
|
||||
"redacted_thinking",
|
||||
|
|
@ -2696,8 +2695,10 @@ def anthropic_messages_pt( # noqa: PLR0915
|
|||
thinking_blocks is not None and not _list_has_thinking
|
||||
): # IMPORTANT: ADD THIS FIRST, ELSE ANTHROPIC WILL RAISE AN ERROR
|
||||
assistant_content.extend(thinking_blocks)
|
||||
if _content_is_list:
|
||||
for m in assistant_content_block["content"]:
|
||||
if _content_is_list and _content_list is not None:
|
||||
for m in _content_list:
|
||||
if not isinstance(m, dict):
|
||||
continue
|
||||
# handle thinking blocks
|
||||
thinking_block = cast(str, m.get("thinking", ""))
|
||||
text_block = cast(str, m.get("text", ""))
|
||||
|
|
|
|||
|
|
@ -50,6 +50,38 @@ class AnthropicMessagesConfig(BaseAnthropicMessagesConfig):
|
|||
# "metadata",
|
||||
]
|
||||
|
||||
def _remove_scope_from_cache_control(
|
||||
self, anthropic_messages_request: Dict
|
||||
) -> None:
|
||||
"""
|
||||
Remove `scope` field from cache_control blocks.
|
||||
|
||||
Some providers (Vertex AI, Azure AI Foundry) do not support the `scope`
|
||||
field in cache_control (e.g. "global" for cross-request caching).
|
||||
Processes both `system` and `messages` content blocks.
|
||||
"""
|
||||
|
||||
def _sanitize(cache_control: Any) -> None:
|
||||
if isinstance(cache_control, dict):
|
||||
cache_control.pop("scope", None)
|
||||
|
||||
def _process_content_list(content: list) -> None:
|
||||
for item in content:
|
||||
if isinstance(item, dict) and "cache_control" in item:
|
||||
_sanitize(item["cache_control"])
|
||||
|
||||
if "system" in anthropic_messages_request:
|
||||
system = anthropic_messages_request["system"]
|
||||
if isinstance(system, list):
|
||||
_process_content_list(system)
|
||||
|
||||
if "messages" in anthropic_messages_request:
|
||||
for message in anthropic_messages_request["messages"]:
|
||||
if isinstance(message, dict) and "content" in message:
|
||||
content = message["content"]
|
||||
if isinstance(content, list):
|
||||
_process_content_list(content)
|
||||
|
||||
@staticmethod
|
||||
def _filter_billing_headers_from_system(system_param):
|
||||
"""
|
||||
|
|
|
|||
|
|
@ -14,7 +14,7 @@ Anthropic Files API endpoints:
|
|||
|
||||
import calendar
|
||||
import time
|
||||
from typing import Any, Dict, List, Optional, Union
|
||||
from typing import Any, Dict, List, Optional, Union, cast
|
||||
|
||||
import httpx
|
||||
from openai.types.file_deleted import FileDeleted
|
||||
|
|
@ -79,7 +79,7 @@ class AnthropicFilesConfig(BaseFilesConfig):
|
|||
return AnthropicError(
|
||||
status_code=status_code,
|
||||
message=error_message,
|
||||
headers=headers,
|
||||
headers=cast(httpx.Headers, headers) if isinstance(headers, dict) else headers,
|
||||
)
|
||||
|
||||
def validate_environment(
|
||||
|
|
|
|||
|
|
@ -152,7 +152,6 @@ class BaseGoogleGenAIGenerateContentConfig(ABC):
|
|||
contents: GenerateContentContentListUnionDict,
|
||||
tools: Optional[ToolConfigDict],
|
||||
generate_content_config_dict: Dict,
|
||||
tool_config: Optional[Dict[str, Any]] = None,
|
||||
system_instruction: Optional[Any] = None,
|
||||
) -> dict:
|
||||
"""
|
||||
|
|
@ -162,7 +161,6 @@ class BaseGoogleGenAIGenerateContentConfig(ABC):
|
|||
model: The model name
|
||||
contents: Input contents
|
||||
tools: Tools
|
||||
tool_config: Tool configuration
|
||||
generate_content_config_dict: Generation config parameters
|
||||
system_instruction: Optional system instruction
|
||||
|
||||
|
|
|
|||
|
|
@ -230,8 +230,8 @@ class BlackForestLabsImageEditConfig(BaseImageEditConfig):
|
|||
def transform_image_edit_request(
|
||||
self,
|
||||
model: str,
|
||||
prompt: str,
|
||||
image: FileTypes,
|
||||
prompt: Optional[str],
|
||||
image: Optional[FileTypes],
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
headers: dict,
|
||||
|
|
|
|||
|
|
@ -259,7 +259,12 @@ class BlackForestLabsImageGenerationConfig(BaseImageGenerationConfig):
|
|||
raw_response: httpx.Response,
|
||||
model_response: ImageResponse,
|
||||
logging_obj: LiteLLMLoggingObj,
|
||||
**kwargs,
|
||||
request_data: dict,
|
||||
optional_params: dict,
|
||||
litellm_params: dict,
|
||||
encoding: Any,
|
||||
api_key: Optional[str] = None,
|
||||
json_mode: Optional[bool] = None,
|
||||
) -> ImageResponse:
|
||||
"""
|
||||
Transform Black Forest Labs response to OpenAI-compatible ImageResponse.
|
||||
|
|
|
|||
|
|
@ -5,7 +5,7 @@ Documentation: https://api-dashboard.search.brave.com/app/documentation/web-sear
|
|||
|
||||
from __future__ import annotations
|
||||
from datetime import datetime, timezone
|
||||
from dateutil import parser
|
||||
from dateutil import parser # type: ignore[import-untyped]
|
||||
from typing import Dict, List, Literal, Optional, TypedDict, Union
|
||||
import httpx
|
||||
import re
|
||||
|
|
|
|||
|
|
@ -3036,10 +3036,11 @@ class BaseLLMHTTPHandler:
|
|||
elif isinstance(transformed_request, dict) and "file" in transformed_request:
|
||||
# Handle multipart form-data uploads (e.g., Anthropic Files API)
|
||||
# The dict contains tuples suitable for httpx's `files` parameter
|
||||
file_request = cast(Dict[str, Any], transformed_request)
|
||||
upload_response = sync_httpx_client.post(
|
||||
url=api_base,
|
||||
headers=headers,
|
||||
files=transformed_request,
|
||||
files=file_request,
|
||||
timeout=timeout,
|
||||
)
|
||||
else:
|
||||
|
|
@ -4870,10 +4871,12 @@ class BaseLLMHTTPHandler:
|
|||
timeout=timeout,
|
||||
)
|
||||
except Exception as e:
|
||||
raise self._handle_error(
|
||||
e=e,
|
||||
provider_config=provider_config,
|
||||
)
|
||||
if provider_config is not None:
|
||||
raise self._handle_error(
|
||||
e=e,
|
||||
provider_config=provider_config,
|
||||
)
|
||||
raise
|
||||
|
||||
async def async_realtime_calls_handler(
|
||||
self,
|
||||
|
|
@ -4954,10 +4957,12 @@ class BaseLLMHTTPHandler:
|
|||
timeout=timeout,
|
||||
)
|
||||
except Exception as e:
|
||||
raise self._handle_error(
|
||||
e=e,
|
||||
provider_config=provider_config,
|
||||
)
|
||||
if provider_config is not None:
|
||||
raise self._handle_error(
|
||||
e=e,
|
||||
provider_config=provider_config,
|
||||
)
|
||||
raise
|
||||
|
||||
async def async_responses_websocket(
|
||||
self,
|
||||
|
|
@ -8026,7 +8031,7 @@ class BaseLLMHTTPHandler:
|
|||
|
||||
url = api_base
|
||||
|
||||
params = {}
|
||||
params: Dict[str, Any] = {}
|
||||
if after is not None:
|
||||
params["after"] = after
|
||||
if before is not None:
|
||||
|
|
@ -8108,7 +8113,7 @@ class BaseLLMHTTPHandler:
|
|||
|
||||
url = api_base
|
||||
|
||||
params = {}
|
||||
params: Dict[str, Any] = {}
|
||||
if after is not None:
|
||||
params["after"] = after
|
||||
if before is not None:
|
||||
|
|
@ -8170,7 +8175,7 @@ class BaseLLMHTTPHandler:
|
|||
|
||||
url = f"{api_base}/{vector_store_id}"
|
||||
|
||||
request_body = dict(vector_store_update_optional_params)
|
||||
request_body: Dict[str, Any] = dict(vector_store_update_optional_params)
|
||||
|
||||
# Clean metadata to only include string values (OpenAI requirement)
|
||||
if "metadata" in request_body and request_body["metadata"] is not None:
|
||||
|
|
@ -8253,7 +8258,7 @@ class BaseLLMHTTPHandler:
|
|||
|
||||
url = f"{api_base}/{vector_store_id}"
|
||||
|
||||
request_body = dict(vector_store_update_optional_params)
|
||||
request_body: Dict[str, Any] = dict(vector_store_update_optional_params)
|
||||
|
||||
# Clean metadata to only include string values (OpenAI requirement)
|
||||
if "metadata" in request_body and request_body["metadata"] is not None:
|
||||
|
|
@ -9329,7 +9334,6 @@ class BaseLLMHTTPHandler:
|
|||
client: Optional[Union[HTTPHandler, AsyncHTTPHandler]] = None,
|
||||
stream: bool = False,
|
||||
litellm_metadata: Optional[Dict[str, Any]] = None,
|
||||
tool_config: Optional[Dict[str, Any]] = None,
|
||||
system_instruction: Optional[Any] = None,
|
||||
) -> Any:
|
||||
"""
|
||||
|
|
@ -9347,7 +9351,6 @@ class BaseLLMHTTPHandler:
|
|||
generate_content_provider_config=generate_content_provider_config,
|
||||
generate_content_config_dict=generate_content_config_dict,
|
||||
tools=tools,
|
||||
tool_config=tool_config,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
litellm_params=litellm_params,
|
||||
logging_obj=logging_obj,
|
||||
|
|
@ -9386,7 +9389,6 @@ class BaseLLMHTTPHandler:
|
|||
model=model,
|
||||
contents=contents,
|
||||
tools=tools,
|
||||
tool_config=tool_config,
|
||||
generate_content_config_dict=generate_content_config_dict,
|
||||
system_instruction=system_instruction,
|
||||
)
|
||||
|
|
@ -9459,7 +9461,6 @@ class BaseLLMHTTPHandler:
|
|||
client: Optional[AsyncHTTPHandler] = None,
|
||||
stream: bool = False,
|
||||
litellm_metadata: Optional[Dict[str, Any]] = None,
|
||||
tool_config: Optional[Dict[str, Any]] = None,
|
||||
system_instruction: Optional[Any] = None,
|
||||
) -> Any:
|
||||
"""
|
||||
|
|
@ -9497,7 +9498,6 @@ class BaseLLMHTTPHandler:
|
|||
model=model,
|
||||
contents=contents,
|
||||
tools=tools,
|
||||
tool_config=tool_config,
|
||||
generate_content_config_dict=generate_content_config_dict,
|
||||
system_instruction=system_instruction,
|
||||
)
|
||||
|
|
|
|||
|
|
@ -308,7 +308,6 @@ class GoogleGenAIConfig(BaseGoogleGenAIGenerateContentConfig, VertexLLM):
|
|||
contents: GenerateContentContentListUnionDict,
|
||||
tools: Optional[ToolConfigDict],
|
||||
generate_content_config_dict: Dict,
|
||||
tool_config: Optional[Dict[str, Any]] = None,
|
||||
system_instruction: Optional[Any] = None,
|
||||
) -> dict:
|
||||
from litellm.types.google_genai.main import (
|
||||
|
|
@ -327,8 +326,6 @@ class GoogleGenAIConfig(BaseGoogleGenAIGenerateContentConfig, VertexLLM):
|
|||
|
||||
if system_instruction is not None:
|
||||
request_dict["systemInstruction"] = system_instruction
|
||||
if tool_config is not None:
|
||||
request_dict["toolConfig"] = tool_config
|
||||
return request_dict
|
||||
|
||||
def transform_generate_content_response(
|
||||
|
|
|
|||
|
|
@ -2,13 +2,15 @@
|
|||
Translates from OpenAI's `/v1/chat/completions` to Moonshot AI's `/v1/chat/completions`
|
||||
"""
|
||||
|
||||
from typing import Any, Coroutine, List, Literal, Optional, Tuple, Union, overload
|
||||
from typing import Any, Coroutine, List, Literal, Optional, Tuple, Union, cast, overload
|
||||
|
||||
import litellm
|
||||
from litellm.litellm_core_utils.prompt_templates.common_utils import (
|
||||
handle_messages_with_content_list_to_str_conversion,
|
||||
)
|
||||
from litellm.secret_managers.main import get_secret_str
|
||||
from litellm.types.llms.openai import AllMessageValues
|
||||
from litellm.utils import supports_reasoning
|
||||
|
||||
from ...openai.chat.gpt_transformation import OpenAIGPTConfig
|
||||
|
||||
|
|
@ -17,8 +19,7 @@ class MoonshotChatConfig(OpenAIGPTConfig):
|
|||
@overload
|
||||
def _transform_messages(
|
||||
self, messages: List[AllMessageValues], model: str, is_async: Literal[True]
|
||||
) -> Coroutine[Any, Any, List[AllMessageValues]]:
|
||||
...
|
||||
) -> Coroutine[Any, Any, List[AllMessageValues]]: ...
|
||||
|
||||
@overload
|
||||
def _transform_messages(
|
||||
|
|
@ -26,8 +27,7 @@ class MoonshotChatConfig(OpenAIGPTConfig):
|
|||
messages: List[AllMessageValues],
|
||||
model: str,
|
||||
is_async: Literal[False] = False,
|
||||
) -> List[AllMessageValues]:
|
||||
...
|
||||
) -> List[AllMessageValues]: ...
|
||||
|
||||
def _transform_messages(
|
||||
self, messages: List[AllMessageValues], model: str, is_async: bool = False
|
||||
|
|
@ -53,22 +53,14 @@ class MoonshotChatConfig(OpenAIGPTConfig):
|
|||
messages = handle_messages_with_content_list_to_str_conversion(messages)
|
||||
|
||||
if is_async:
|
||||
return super()._transform_messages(
|
||||
messages=messages, model=model, is_async=True
|
||||
)
|
||||
return super()._transform_messages(messages=messages, model=model, is_async=True)
|
||||
else:
|
||||
return super()._transform_messages(
|
||||
messages=messages, model=model, is_async=False
|
||||
)
|
||||
return super()._transform_messages(messages=messages, model=model, is_async=False)
|
||||
|
||||
def _get_openai_compatible_provider_info(
|
||||
self, api_base: Optional[str], api_key: Optional[str]
|
||||
) -> Tuple[Optional[str], Optional[str]]:
|
||||
api_base = (
|
||||
api_base
|
||||
or get_secret_str("MOONSHOT_API_BASE")
|
||||
or "https://api.moonshot.ai/v1"
|
||||
) # type: ignore
|
||||
api_base = api_base or get_secret_str("MOONSHOT_API_BASE") or "https://api.moonshot.ai/v1" # type: ignore
|
||||
dynamic_api_key = api_key or get_secret_str("MOONSHOT_API_KEY")
|
||||
return api_base, dynamic_api_key
|
||||
|
||||
|
|
@ -149,6 +141,48 @@ class MoonshotChatConfig(OpenAIGPTConfig):
|
|||
optional_params["temperature"] = 0.3
|
||||
return optional_params
|
||||
|
||||
def fill_reasoning_content(self, messages: List[AllMessageValues]) -> List[AllMessageValues]:
|
||||
"""
|
||||
Moonshot reasoning models require `reasoning_content` on every assistant
|
||||
message that contains tool_calls (multi-turn tool-calling flows).
|
||||
|
||||
For each such message that is missing the field:
|
||||
1. Promote provider_specific_fields["reasoning_content"] if present and non-empty
|
||||
(this is where LiteLLM stores it from a previous response)
|
||||
2. Otherwise inject a single space — the minimum value the API accepts
|
||||
Messages that already carry the field, or are not assistant/tool-call messages,
|
||||
are appended as-is (no copy made).
|
||||
"""
|
||||
result: List[AllMessageValues] = []
|
||||
for msg in messages:
|
||||
if (
|
||||
msg.get("role") == "assistant"
|
||||
and msg.get("tool_calls")
|
||||
and "reasoning_content" not in msg
|
||||
):
|
||||
patched = dict(cast(dict, msg))
|
||||
provider_fields = patched.get("provider_specific_fields") or {}
|
||||
stored = provider_fields.get("reasoning_content")
|
||||
if stored:
|
||||
patched["reasoning_content"] = stored
|
||||
# Remove the promoted key from provider_specific_fields to
|
||||
# avoid sending the value twice in the serialised request body
|
||||
cleaned_provider_fields = dict(provider_fields)
|
||||
cleaned_provider_fields.pop("reasoning_content", None)
|
||||
patched["provider_specific_fields"] = cleaned_provider_fields
|
||||
else:
|
||||
litellm.verbose_logger.warning(
|
||||
"Moonshot reasoning model: assistant tool-call message is missing "
|
||||
"`reasoning_content`. Injecting a placeholder to satisfy API validation. "
|
||||
"For best results, preserve `reasoning_content` from the original "
|
||||
"assistant response when building multi-turn conversation history."
|
||||
)
|
||||
patched["reasoning_content"] = " "
|
||||
result.append(cast(AllMessageValues, patched))
|
||||
else:
|
||||
result.append(msg)
|
||||
return result
|
||||
|
||||
def transform_request(
|
||||
self,
|
||||
model: str,
|
||||
|
|
@ -169,6 +203,10 @@ class MoonshotChatConfig(OpenAIGPTConfig):
|
|||
optional_params=optional_params,
|
||||
)
|
||||
|
||||
# Moonshot reasoning models: fill in reasoning_content before the API call
|
||||
if supports_reasoning(model=model, custom_llm_provider="moonshot"):
|
||||
messages = self.fill_reasoning_content(messages)
|
||||
|
||||
# Call parent transform_request which handles _transform_messages
|
||||
return super().transform_request(
|
||||
model=model,
|
||||
|
|
|
|||
|
|
@ -188,11 +188,9 @@ class OpenAIGPT5Config(OpenAIGPTConfig):
|
|||
) or optional_params.get("reasoning_effort")
|
||||
effective_effort = _get_effort_level(raw_reasoning_effort)
|
||||
|
||||
# Normalize to string for Chat Completions API when dict has only "effort".
|
||||
# Preserve full dict (e.g. {"effort": "high", "summary": "detailed"}) for Responses API.
|
||||
if isinstance(raw_reasoning_effort, dict) and set(
|
||||
raw_reasoning_effort.keys()
|
||||
) <= {"effort"}:
|
||||
# Normalize dict reasoning_effort to string for Chat Completions API.
|
||||
# Example: {"effort": "high", "summary": "detailed"} -> "high"
|
||||
if isinstance(raw_reasoning_effort, dict) and "effort" in raw_reasoning_effort:
|
||||
normalized = _normalize_reasoning_effort_for_chat_completion(
|
||||
raw_reasoning_effort
|
||||
)
|
||||
|
|
@ -223,16 +221,6 @@ class OpenAIGPT5Config(OpenAIGPTConfig):
|
|||
"max_tokens"
|
||||
)
|
||||
|
||||
# gpt-5.4: reasoning_effort + tools is only supported in the Responses API
|
||||
# Drop reasoning_effort when tools are present in chat completions
|
||||
if self.is_model_gpt_5_4_model(model):
|
||||
has_tools = bool(
|
||||
non_default_params.get("tools") or optional_params.get("tools")
|
||||
)
|
||||
if has_tools and effective_effort is not None:
|
||||
non_default_params.pop("reasoning_effort", None)
|
||||
optional_params.pop("reasoning_effort", None)
|
||||
|
||||
# gpt-5.1/5.2 support logprobs, top_p, top_logprobs only when reasoning_effort="none"
|
||||
supports_none = self._supports_reasoning_effort_level(model, "none")
|
||||
if supports_none:
|
||||
|
|
|
|||
|
|
@ -63,16 +63,19 @@ class PerplexityResponsesConfig(OpenAIResponsesAPIConfig):
|
|||
|
||||
def _ensure_message_type(
|
||||
self, input: Union[str, ResponseInputParam]
|
||||
) -> Union[str, List[Dict[str, Any]]]:
|
||||
) -> Union[str, ResponseInputParam]:
|
||||
"""Ensure list input items have type='message' (required by Perplexity)."""
|
||||
if isinstance(input, str):
|
||||
return input
|
||||
if isinstance(input, list):
|
||||
result = []
|
||||
result: List[Any] = []
|
||||
for item in input:
|
||||
if isinstance(item, dict) and "type" not in item:
|
||||
item = {**item, "type": "message"}
|
||||
result.append(item)
|
||||
new_item = dict(item) # convert to plain dict to avoid TypedDict checking
|
||||
new_item["type"] = "message"
|
||||
result.append(new_item)
|
||||
else:
|
||||
result.append(item)
|
||||
return result
|
||||
return input
|
||||
|
||||
|
|
|
|||
|
|
@ -153,6 +153,7 @@ class GoogleBatchEmbeddings(VertexLLM):
|
|||
|
||||
is_multimodal = _is_multimodal_input(input)
|
||||
use_embed_content = is_multimodal or (custom_llm_provider == "vertex_ai")
|
||||
mode: Literal["embedding", "batch_embedding"]
|
||||
if use_embed_content:
|
||||
mode = "embedding"
|
||||
else:
|
||||
|
|
@ -200,6 +201,7 @@ class GoogleBatchEmbeddings(VertexLLM):
|
|||
)
|
||||
|
||||
### TRANSFORMATION (sync path) ###
|
||||
request_data: Any
|
||||
if use_embed_content:
|
||||
resolved_files = {}
|
||||
if api_key:
|
||||
|
|
|
|||
|
|
@ -73,7 +73,6 @@ class VertexAIGoogleGenAIConfig(GoogleGenAIConfig):
|
|||
contents: Any,
|
||||
tools: Optional[Any],
|
||||
generate_content_config_dict: Dict,
|
||||
tool_config: Optional[Dict[str, Any]] = None,
|
||||
system_instruction: Optional[Any] = None,
|
||||
) -> dict:
|
||||
"""
|
||||
|
|
@ -90,11 +89,8 @@ class VertexAIGoogleGenAIConfig(GoogleGenAIConfig):
|
|||
if tools:
|
||||
result["tools"] = tools
|
||||
|
||||
if tool_config is not None:
|
||||
result["toolConfig"] = tool_config
|
||||
|
||||
# Add systemInstruction if provided
|
||||
if system_instruction is not None:
|
||||
if system_instruction:
|
||||
result["systemInstruction"] = system_instruction
|
||||
|
||||
# Handle generationConfig - Vertex AI expects it in the same format
|
||||
|
|
|
|||
|
|
@ -150,6 +150,8 @@ class VertexAIPartnerModelsAnthropicMessagesConfig(AnthropicMessagesConfig, Vert
|
|||
headers=headers,
|
||||
)
|
||||
|
||||
self._remove_scope_from_cache_control(anthropic_messages_request)
|
||||
|
||||
anthropic_messages_request["anthropic_version"] = "vertex-2023-10-16"
|
||||
|
||||
anthropic_messages_request.pop(
|
||||
|
|
|
|||
|
|
@ -190,7 +190,7 @@ class VertexAILlama3StreamingHandler(OpenAIChatCompletionStreamingHandler):
|
|||
],
|
||||
)
|
||||
# Modify current chunk to be the first chunk with role but no finish_reason
|
||||
result.choices[0].finish_reason = None
|
||||
result.choices[0].finish_reason = None # type: ignore[assignment]
|
||||
delta.role = "assistant"
|
||||
# Ensure content is empty string for first chunk, not None
|
||||
if delta.content is None:
|
||||
|
|
|
|||
|
|
@ -99,6 +99,7 @@ from litellm.llms.base_llm.base_model_iterator import (
|
|||
from litellm.llms.bedrock.common_utils import BedrockModelInfo
|
||||
from litellm.llms.cohere.common_utils import CohereModelInfo
|
||||
from litellm.llms.custom_httpx.http_handler import AsyncHTTPHandler, HTTPHandler
|
||||
from litellm.llms.openai.chat.gpt_5_transformation import OpenAIGPT5Config
|
||||
from litellm.llms.openai_like.json_loader import JSONProviderRegistry
|
||||
from litellm.llms.vertex_ai.common_utils import (
|
||||
VertexAIModelRoute,
|
||||
|
|
@ -934,6 +935,8 @@ def responses_api_bridge_check(
|
|||
model: str,
|
||||
custom_llm_provider: str,
|
||||
web_search_options: Optional[OpenAIWebSearchOptions] = None,
|
||||
tools: Optional[List[Any]] = None,
|
||||
reasoning_effort: Optional[Any] = None,
|
||||
) -> Tuple[dict, str]:
|
||||
model_info: Dict[str, Any] = {}
|
||||
try:
|
||||
|
|
@ -951,6 +954,17 @@ def responses_api_bridge_check(
|
|||
if web_search_options is not None and custom_llm_provider == "xai":
|
||||
model_info["mode"] = "responses"
|
||||
model = model.replace("responses/", "")
|
||||
|
||||
# OpenAI gpt-5.4+ chat-completions calls with both tools + reasoning_effort
|
||||
# must be bridged to Responses API.
|
||||
if (
|
||||
custom_llm_provider == "openai"
|
||||
and OpenAIGPT5Config.is_model_gpt_5_4_plus_model(model)
|
||||
and tools
|
||||
and reasoning_effort is not None
|
||||
):
|
||||
model_info["mode"] = "responses"
|
||||
model = model.replace("responses/", "")
|
||||
except Exception as e:
|
||||
verbose_logger.debug("Error getting model info: {}".format(e))
|
||||
|
||||
|
|
@ -1598,10 +1612,22 @@ def completion( # type: ignore # noqa: PLR0915
|
|||
timeout=timeout,
|
||||
)
|
||||
|
||||
## RESPONSES API BRIDGE LOGIC ## - check if model has 'mode: responses' in litellm.model_cost map
|
||||
model_info, model = responses_api_bridge_check(
|
||||
model=model,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
web_search_options=web_search_options,
|
||||
tools=tools,
|
||||
reasoning_effort=reasoning_effort,
|
||||
)
|
||||
|
||||
if responses_api_model_info.get("mode") == "responses":
|
||||
from litellm.completion_extras import responses_api_bridge
|
||||
|
||||
if isinstance(reasoning_effort, dict) and "summary" in reasoning_effort:
|
||||
optional_params = dict(optional_params)
|
||||
optional_params["reasoning_effort"] = reasoning_effort
|
||||
|
||||
return responses_api_bridge.completion(
|
||||
model=model,
|
||||
messages=messages,
|
||||
|
|
@ -5103,6 +5129,7 @@ def embedding( # noqa: PLR0915
|
|||
client=client,
|
||||
aembedding=aembedding,
|
||||
litellm_params=litellm_params_dict,
|
||||
headers=headers,
|
||||
)
|
||||
elif custom_llm_provider == "bedrock":
|
||||
if isinstance(input, str):
|
||||
|
|
@ -7701,7 +7728,7 @@ async def acount_tokens(
|
|||
local_count = litellm.token_counter(
|
||||
model=model,
|
||||
messages=fallback_messages,
|
||||
tools=tools,
|
||||
tools=tools, # type: ignore[arg-type]
|
||||
)
|
||||
|
||||
return TokenCountResponse(
|
||||
|
|
|
|||
|
|
@ -22083,6 +22083,7 @@
|
|||
"output_cost_per_token": 3e-06,
|
||||
"source": "https://platform.moonshot.ai/docs/guide/kimi-k2-5-quickstart",
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_video_input": true,
|
||||
"supports_vision": true
|
||||
|
|
@ -22166,6 +22167,7 @@
|
|||
"output_cost_per_token": 2.5e-06,
|
||||
"source": "https://platform.moonshot.ai/docs/pricing/chat#generation-model-kimi-k2",
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_web_search": true
|
||||
},
|
||||
|
|
@ -22180,6 +22182,7 @@
|
|||
"output_cost_per_token": 8e-06,
|
||||
"source": "https://platform.moonshot.ai/docs/pricing/chat#generation-model-kimi-k2",
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_web_search": true
|
||||
},
|
||||
|
|
|
|||
|
|
@ -142,9 +142,9 @@ def decrypt_credentials(
|
|||
"aws_session_token",
|
||||
]
|
||||
for field in secret_fields:
|
||||
value = credentials.get(field)
|
||||
if value is not None:
|
||||
credentials[field] = decrypt_value_helper(
|
||||
value = credentials.get(field) # type: ignore[literal-required]
|
||||
if value is not None and isinstance(value, str):
|
||||
credentials[field] = decrypt_value_helper( # type: ignore[literal-required]
|
||||
value=value,
|
||||
key=field,
|
||||
exception_type="debug",
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
import importlib
|
||||
from datetime import datetime
|
||||
from typing import Any, Awaitable, Callable, Dict, List, Optional, Set, Union
|
||||
from typing import Any, Awaitable, Callable, Dict, List, Literal, Optional, Set, Union
|
||||
|
||||
from fastapi import APIRouter, Depends, HTTPException, Query, Request
|
||||
|
||||
|
|
@ -905,6 +905,12 @@ if MCP_AVAILABLE:
|
|||
try:
|
||||
client_id, client_secret, scopes = _extract_credentials(request)
|
||||
|
||||
_oauth2_flow: Optional[Literal["client_credentials", "authorization_code"]] = (
|
||||
"client_credentials"
|
||||
if client_id and client_secret and request.token_url
|
||||
else None
|
||||
)
|
||||
|
||||
server_model = MCPServer(
|
||||
server_id=request.server_id or "",
|
||||
name=request.alias or request.server_name or "",
|
||||
|
|
@ -922,6 +928,7 @@ if MCP_AVAILABLE:
|
|||
scopes=scopes,
|
||||
authorization_url=request.authorization_url,
|
||||
registration_url=request.registration_url,
|
||||
oauth2_flow=_oauth2_flow,
|
||||
)
|
||||
|
||||
stdio_env = global_mcp_server_manager._build_stdio_env(
|
||||
|
|
|
|||
|
|
@ -484,6 +484,7 @@ class LiteLLMRoutes(enum.Enum):
|
|||
"/organization/list",
|
||||
"/team/available",
|
||||
"/user/info",
|
||||
"/v2/user/info",
|
||||
"/model/info",
|
||||
"/v1/model/info",
|
||||
"/v2/model/info",
|
||||
|
|
@ -1006,6 +1007,7 @@ class UpdateKeyRequest(KeyRequestBase):
|
|||
temp_budget_expiry: Optional[datetime] = None
|
||||
auto_rotate: Optional[bool] = None
|
||||
rotation_interval: Optional[str] = None
|
||||
organization_id: Optional[str] = None
|
||||
|
||||
@model_validator(mode="after")
|
||||
def validate_temp_budget(self) -> "UpdateKeyRequest":
|
||||
|
|
@ -2561,6 +2563,30 @@ class UserInfoResponse(LiteLLMPydanticObjectBase):
|
|||
teams: List
|
||||
|
||||
|
||||
class UserInfoV2Response(LiteLLMPydanticObjectBase):
|
||||
"""
|
||||
Response model for GET /v2/user/info
|
||||
|
||||
Returns ONLY the user object - no keys, no teams objects.
|
||||
This is a lightweight alternative to UserInfoResponse.
|
||||
"""
|
||||
|
||||
user_id: str
|
||||
user_email: Optional[str] = None
|
||||
user_alias: Optional[str] = None
|
||||
user_role: Optional[str] = None
|
||||
spend: float = 0.0
|
||||
max_budget: Optional[float] = None
|
||||
models: List[str] = []
|
||||
budget_duration: Optional[str] = None
|
||||
budget_reset_at: Optional[datetime] = None
|
||||
metadata: Optional[dict] = None
|
||||
created_at: Optional[datetime] = None
|
||||
updated_at: Optional[datetime] = None
|
||||
sso_user_id: Optional[str] = None
|
||||
teams: List[str] = [] # Just team IDs, not full team objects
|
||||
|
||||
|
||||
class LiteLLM_Config(LiteLLMPydanticObjectBase):
|
||||
param_name: str
|
||||
param_value: Dict
|
||||
|
|
|
|||
|
|
@ -402,7 +402,7 @@ async def common_checks( # noqa: PLR0915
|
|||
# 1. If team is blocked
|
||||
if team_object is not None and team_object.blocked is True:
|
||||
raise Exception(
|
||||
f"Team={team_object.team_id} is blocked. Update via `/team/unblock` if your admin."
|
||||
f"Team={team_object.team_id} is blocked. Update via `/team/unblock` if you're an admin."
|
||||
)
|
||||
|
||||
# 2. If team can call model
|
||||
|
|
|
|||
|
|
@ -183,6 +183,9 @@ class RouteChecks:
|
|||
user_id, valid_token.user_id
|
||||
),
|
||||
)
|
||||
elif route == "/v2/user/info":
|
||||
# handled by the endpoint itself (full RBAC in handler)
|
||||
pass
|
||||
elif route == "/model/info":
|
||||
# /model/info just shows models user has access to
|
||||
pass
|
||||
|
|
|
|||
|
|
@ -1175,7 +1175,7 @@ async def _user_api_key_auth_builder( # noqa: PLR0915
|
|||
## base case ## key is disabled
|
||||
if valid_token.blocked is True:
|
||||
raise Exception(
|
||||
"Key is blocked. Update via `/key/unblock` if you're admin."
|
||||
"Key is blocked. Update via `/key/unblock` if you're an admin."
|
||||
)
|
||||
config = valid_token.config
|
||||
|
||||
|
|
|
|||
|
|
@ -37,6 +37,18 @@ class UsersManagementClient:
|
|||
response.raise_for_status()
|
||||
return response.json()
|
||||
|
||||
def get_user_v2(self, user_id: Optional[str] = None) -> Dict[str, Any]:
|
||||
"""Get user info v2 - lightweight, returns only user object (GET /v2/user/info)"""
|
||||
url = f"{self.base_url}/v2/user/info"
|
||||
params = {"user_id": user_id} if user_id else {}
|
||||
response = requests.get(url, headers=self._get_headers(), params=params)
|
||||
if response.status_code == 401:
|
||||
raise UnauthorizedError(response.text)
|
||||
if response.status_code == 404:
|
||||
raise NotFoundError(response.text)
|
||||
response.raise_for_status()
|
||||
return response.json()
|
||||
|
||||
def create_user(self, user_data: Dict[str, Any]) -> Dict[str, Any]:
|
||||
"""Create a new user (POST /user/new)"""
|
||||
url = f"{self.base_url}/user/new"
|
||||
|
|
|
|||
|
|
@ -25,6 +25,7 @@ from litellm._logging import verbose_proxy_logger
|
|||
from litellm._uuid import uuid
|
||||
from litellm.constants import (
|
||||
DD_TRACER_STREAMING_CHUNK_YIELD_RESOURCE,
|
||||
DEFAULT_MAX_RECURSE_DEPTH,
|
||||
LITELLM_DETAILED_TIMING,
|
||||
MAX_PAYLOAD_SIZE_FOR_DEBUG_LOG,
|
||||
STREAM_SSE_DATA_PREFIX,
|
||||
|
|
@ -384,6 +385,32 @@ def _get_cost_breakdown_from_logging_obj(
|
|||
return original_cost, discount_amount, margin_total_amount, margin_percent
|
||||
|
||||
|
||||
def _has_attribute_error_in_chain(exc: Exception) -> bool:
|
||||
"""Walk the exception chain to find an AttributeError at any depth.
|
||||
|
||||
Checks __cause__, __context__, and the litellm-specific original_exception
|
||||
attribute iteratively. Depth is capped at DEFAULT_MAX_RECURSE_DEPTH to
|
||||
avoid infinite loops from circular exception references.
|
||||
"""
|
||||
stack: list[BaseException] = [exc]
|
||||
seen: set[int] = set()
|
||||
depth = 0
|
||||
while stack and depth < DEFAULT_MAX_RECURSE_DEPTH:
|
||||
current = stack.pop()
|
||||
exc_id = id(current)
|
||||
if exc_id in seen:
|
||||
continue
|
||||
seen.add(exc_id)
|
||||
if isinstance(current, AttributeError):
|
||||
return True
|
||||
for attr in ("__cause__", "__context__", "original_exception"):
|
||||
inner = getattr(current, attr, None)
|
||||
if inner is not None and isinstance(inner, BaseException):
|
||||
stack.append(inner)
|
||||
depth += 1
|
||||
return False
|
||||
|
||||
|
||||
class ProxyBaseLLMRequestProcessing:
|
||||
def __init__(self, data: dict):
|
||||
self.data = data
|
||||
|
|
@ -530,6 +557,8 @@ class ProxyBaseLLMRequestProcessing:
|
|||
"aresponses",
|
||||
"_arealtime",
|
||||
"_aresponses_websocket",
|
||||
"acreate_realtime_client_secret",
|
||||
"arealtime_calls",
|
||||
"aget_responses",
|
||||
"adelete_responses",
|
||||
"acancel_responses",
|
||||
|
|
@ -553,6 +582,10 @@ class ProxyBaseLLMRequestProcessing:
|
|||
"allm_passthrough_route",
|
||||
"avector_store_search",
|
||||
"avector_store_create",
|
||||
"avector_store_retrieve",
|
||||
"avector_store_list",
|
||||
"avector_store_update",
|
||||
"avector_store_delete",
|
||||
"avector_store_file_create",
|
||||
"avector_store_file_list",
|
||||
"avector_store_file_retrieve",
|
||||
|
|
@ -774,20 +807,36 @@ class ProxyBaseLLMRequestProcessing:
|
|||
"aembedding",
|
||||
"aresponses",
|
||||
"_arealtime",
|
||||
"_aresponses_websocket",
|
||||
"acreate_realtime_client_secret",
|
||||
"arealtime_calls",
|
||||
"aget_responses",
|
||||
"adelete_responses",
|
||||
"acancel_responses",
|
||||
"acompact_responses",
|
||||
"acreate_batch",
|
||||
"aretrieve_batch",
|
||||
"alist_batches",
|
||||
"acancel_batch",
|
||||
"afile_content",
|
||||
"afile_retrieve",
|
||||
"afile_delete",
|
||||
"atext_completion",
|
||||
"aimage_edit",
|
||||
"acreate_fine_tuning_job",
|
||||
"acancel_fine_tuning_job",
|
||||
"alist_fine_tuning_jobs",
|
||||
"aretrieve_fine_tuning_job",
|
||||
"alist_input_items",
|
||||
"aimage_edit",
|
||||
"agenerate_content",
|
||||
"agenerate_content_stream",
|
||||
"allm_passthrough_route",
|
||||
"avector_store_search",
|
||||
"avector_store_create",
|
||||
"avector_store_retrieve",
|
||||
"avector_store_list",
|
||||
"avector_store_update",
|
||||
"avector_store_delete",
|
||||
"avector_store_file_create",
|
||||
"avector_store_file_list",
|
||||
"avector_store_file_retrieve",
|
||||
|
|
@ -815,8 +864,8 @@ class ProxyBaseLLMRequestProcessing:
|
|||
"aget_interaction",
|
||||
"adelete_interaction",
|
||||
"acancel_interaction",
|
||||
"acancel_batch",
|
||||
"afile_delete",
|
||||
"asend_message",
|
||||
"call_mcp_tool",
|
||||
"acreate_eval",
|
||||
"alist_evals",
|
||||
"aget_eval",
|
||||
|
|
@ -1259,23 +1308,11 @@ class ProxyBaseLLMRequestProcessing:
|
|||
detail={"error": error_text},
|
||||
)
|
||||
error_msg = f"{str(e)}"
|
||||
# Check for AttributeError in various places:
|
||||
# 1. Direct AttributeError (already handled above)
|
||||
# 2. In underlying exception (__cause__, __context__, original_exception)
|
||||
has_attribute_error = (
|
||||
(
|
||||
isinstance(e, Exception)
|
||||
and isinstance(getattr(e, "__cause__", None), AttributeError)
|
||||
)
|
||||
or (
|
||||
isinstance(e, Exception)
|
||||
and isinstance(getattr(e, "__context__", None), AttributeError)
|
||||
)
|
||||
or (
|
||||
isinstance(e, Exception)
|
||||
and isinstance(getattr(e, "original_exception", None), AttributeError)
|
||||
)
|
||||
)
|
||||
# Check for AttributeError in the exception chain.
|
||||
# The AttributeError may be wrapped in multiple layers
|
||||
# (e.g. AttributeError -> OpenAIException -> APIConnectionError),
|
||||
# so walk __cause__, __context__, and original_exception recursively.
|
||||
has_attribute_error = _has_attribute_error_in_chain(e)
|
||||
|
||||
if has_attribute_error:
|
||||
raise ProxyException(
|
||||
|
|
|
|||
|
|
@ -1,7 +1,7 @@
|
|||
model_list:
|
||||
- model_name: fake-openai-endpoint
|
||||
litellm_params:
|
||||
model: openai/gpt-3.5-turbo-0301
|
||||
model: openai/gpt-3.5-turbo
|
||||
api_key: fake-key
|
||||
api_base: https://exampleopenaiendpoint-production.up.railway.app/
|
||||
tags: ["teamA"]
|
||||
|
|
@ -9,7 +9,7 @@ model_list:
|
|||
id: "team-a-model"
|
||||
- model_name: fake-openai-endpoint
|
||||
litellm_params:
|
||||
model: openai/gpt-3.5-turbo-0301
|
||||
model: openai/gpt-3.5-turbo
|
||||
api_key: fake-key
|
||||
api_base: https://exampleopenaiendpoint-production.up.railway.app/
|
||||
tags: ["teamB"]
|
||||
|
|
|
|||
|
|
@ -1,7 +1,7 @@
|
|||
model_list:
|
||||
- model_name: fake-openai-endpoint
|
||||
litellm_params:
|
||||
model: openai/gpt-3.5-turbo-0301
|
||||
model: openai/gpt-3.5-turbo
|
||||
api_key: fake-key
|
||||
api_base: https://exampleopenaiendpoint-production.up.railway.app/
|
||||
|
||||
|
|
|
|||
|
|
@ -315,6 +315,7 @@ class PanwPrismaAirsHandler(CustomGuardrail):
|
|||
panw_metadata["litellm_trace_id"] = metadata["litellm_trace_id"]
|
||||
|
||||
# Build contents: tool_event takes priority, else prompt/response text
|
||||
contents: List[Dict[str, Any]]
|
||||
if tool_event is not None:
|
||||
contents = [{"tool_event": tool_event}]
|
||||
else:
|
||||
|
|
@ -1485,7 +1486,7 @@ class PanwPrismaAirsHandler(CustomGuardrail):
|
|||
detail = (
|
||||
e.detail if isinstance(e.detail, dict) else {"message": str(e.detail)}
|
||||
)
|
||||
error_obj = dict(detail.get("error", detail))
|
||||
error_obj: Dict[str, Any] = dict(detail.get("error", detail)) # type: ignore[arg-type]
|
||||
error_obj["code"] = e.status_code
|
||||
yield f"data: {json.dumps({'error': error_obj})}\n\n"
|
||||
except Exception as e:
|
||||
|
|
|
|||
|
|
@ -106,9 +106,9 @@ class _OPTIONAL_PresidioPIIMasking(CustomGuardrail):
|
|||
if (self.output_parse_pii or self.apply_to_output) and not logging_only:
|
||||
current_hook = self.event_hook
|
||||
if isinstance(current_hook, str) and current_hook != "post_call":
|
||||
self.event_hook = [current_hook, "post_call"]
|
||||
self.event_hook = cast(List[GuardrailEventHooks], [current_hook, "post_call"])
|
||||
elif isinstance(current_hook, list) and "post_call" not in current_hook:
|
||||
self.event_hook = current_hook + ["post_call"]
|
||||
self.event_hook = cast(List[GuardrailEventHooks], current_hook + ["post_call"])
|
||||
self.pii_entities_config: Dict[Union[PiiEntityType, str], PiiAction] = (
|
||||
pii_entities_config or {}
|
||||
)
|
||||
|
|
@ -908,7 +908,7 @@ class _OPTIONAL_PresidioPIIMasking(CustomGuardrail):
|
|||
if self.apply_to_output is True:
|
||||
if self._is_anthropic_message_response(response):
|
||||
return await self._process_anthropic_response_for_pii(
|
||||
response=response, request_data=data, mode="mask"
|
||||
response=cast(dict, response), request_data=data, mode="mask"
|
||||
)
|
||||
return await self._mask_output_response(
|
||||
response=response, request_data=data
|
||||
|
|
@ -927,7 +927,7 @@ class _OPTIONAL_PresidioPIIMasking(CustomGuardrail):
|
|||
)
|
||||
elif self._is_anthropic_message_response(response):
|
||||
await self._process_anthropic_response_for_pii(
|
||||
response=response, request_data=data, mode="unmask"
|
||||
response=cast(dict, response), request_data=data, mode="unmask"
|
||||
)
|
||||
return response
|
||||
|
||||
|
|
@ -1229,7 +1229,7 @@ class _OPTIONAL_PresidioPIIMasking(CustomGuardrail):
|
|||
for chunk in remaining_chunks:
|
||||
yield chunk
|
||||
|
||||
async def async_post_call_streaming_iterator_hook(
|
||||
async def async_post_call_streaming_iterator_hook( # type: ignore[override]
|
||||
self,
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
response: Any,
|
||||
|
|
@ -1237,6 +1237,10 @@ class _OPTIONAL_PresidioPIIMasking(CustomGuardrail):
|
|||
) -> AsyncGenerator[Union[ModelResponseStream, bytes], None]:
|
||||
"""
|
||||
Process streaming response chunks to unmask PII tokens when needed.
|
||||
|
||||
Note: the return type includes `bytes` because Anthropic native SSE
|
||||
streaming sends raw bytes chunks that pass through untransformed.
|
||||
The base class declares ModelResponseStream only.
|
||||
"""
|
||||
if self.apply_to_output:
|
||||
async for chunk in self._stream_apply_output_masking(
|
||||
|
|
|
|||
|
|
@ -259,6 +259,7 @@ class SemanticToolFilterHook(CustomLogger):
|
|||
user_api_key_dict: "UserAPIKeyAuth",
|
||||
response: Any,
|
||||
request_headers: Optional[Dict[str, str]] = None,
|
||||
litellm_call_info: Optional[Dict[str, Any]] = None,
|
||||
) -> Optional[Dict[str, str]]:
|
||||
"""Add semantic filter stats and tool names to response headers."""
|
||||
from litellm.constants import MAX_MCP_SEMANTIC_FILTER_TOOLS_HEADER_LENGTH
|
||||
|
|
|
|||
|
|
@ -31,7 +31,10 @@ from litellm.proxy.management_endpoints.common_daily_activity import (
|
|||
get_daily_activity_aggregated,
|
||||
)
|
||||
from litellm.proxy.auth.auth_checks import get_team_object, get_user_object
|
||||
from litellm.proxy.management_endpoints.common_utils import _user_has_admin_view
|
||||
from litellm.proxy.management_endpoints.common_utils import (
|
||||
_is_user_team_admin,
|
||||
_user_has_admin_view,
|
||||
)
|
||||
from litellm.proxy.management_endpoints.key_management_endpoints import (
|
||||
generate_key_helper_fn,
|
||||
prepare_metadata_fields,
|
||||
|
|
@ -720,6 +723,166 @@ async def user_info(
|
|||
raise handle_exception_on_proxy(e)
|
||||
|
||||
|
||||
async def _check_user_info_v2_access(
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
target_user_id: str,
|
||||
) -> Optional["LiteLLM_UserTable"]:
|
||||
"""
|
||||
Check if the caller is allowed to access the target user's info.
|
||||
|
||||
Returns the target user's DB row if access is allowed, None otherwise.
|
||||
Returning the row avoids a redundant DB fetch in the caller.
|
||||
|
||||
Access rules:
|
||||
1. Proxy admins / proxy admin viewers can access any user
|
||||
2. User can access their own info
|
||||
3. Team admins can access info of users in their teams
|
||||
|
||||
Raises on unexpected DB errors so they surface as 500s, not silent 404s.
|
||||
"""
|
||||
from litellm.proxy.proxy_server import prisma_client
|
||||
|
||||
if prisma_client is None:
|
||||
return None
|
||||
|
||||
# Helper: fetch the target user row (reused across branches)
|
||||
async def _fetch_target_user():
|
||||
return await prisma_client.db.litellm_usertable.find_unique(
|
||||
where={"user_id": target_user_id}
|
||||
)
|
||||
|
||||
# Rule 1: Proxy admins — fetch and return the target row directly
|
||||
if _user_has_admin_view(user_api_key_dict):
|
||||
return await _fetch_target_user()
|
||||
|
||||
# Rule 2: Self-lookup
|
||||
if user_api_key_dict.user_id == target_user_id:
|
||||
return await _fetch_target_user()
|
||||
|
||||
# Rule 3: Team admins can look up users in their teams
|
||||
if user_api_key_dict.user_id is not None:
|
||||
# Get caller's teams
|
||||
caller_user = await prisma_client.db.litellm_usertable.find_unique(
|
||||
where={"user_id": user_api_key_dict.user_id}
|
||||
)
|
||||
if caller_user is not None and caller_user.teams:
|
||||
# Fetch the target user ONCE, before the loop
|
||||
target_user = await _fetch_target_user()
|
||||
if target_user is None:
|
||||
return None
|
||||
|
||||
# Get all teams the caller belongs to
|
||||
teams = await prisma_client.db.litellm_teamtable.find_many(
|
||||
where={"team_id": {"in": caller_user.teams}}
|
||||
)
|
||||
for team in teams:
|
||||
team_obj = LiteLLM_TeamTable(**team.model_dump())
|
||||
if _is_user_team_admin(
|
||||
user_api_key_dict=user_api_key_dict, team_obj=team_obj
|
||||
):
|
||||
# Check if target user is in this team
|
||||
if team.team_id in (target_user.teams or []):
|
||||
return target_user
|
||||
|
||||
return None
|
||||
|
||||
|
||||
@router.get(
|
||||
"/v2/user/info",
|
||||
tags=["Internal User management"],
|
||||
dependencies=[Depends(user_api_key_auth)],
|
||||
response_model=UserInfoV2Response,
|
||||
)
|
||||
@management_endpoint_wrapper
|
||||
async def user_info_v2(
|
||||
request: Request,
|
||||
user_id: Optional[str] = fastapi.Query(
|
||||
default=None, description="User ID in the request parameters"
|
||||
),
|
||||
user_api_key_dict: UserAPIKeyAuth = Depends(user_api_key_auth),
|
||||
):
|
||||
"""
|
||||
Lightweight endpoint to get user info. Returns only the user object — no keys, no teams objects.
|
||||
|
||||
This is the v2 replacement for /user/info, designed to avoid the "god endpoint" problem
|
||||
where the old endpoint loaded all keys and teams into memory.
|
||||
|
||||
Access control:
|
||||
- Proxy admins can query any user
|
||||
- Team admins can query users within their teams
|
||||
- Internal users can only query themselves (omit user_id or pass own)
|
||||
- Returns 404 for non-existent users or unauthorized access
|
||||
|
||||
Example request:
|
||||
```
|
||||
curl -X GET 'http://localhost:4000/v2/user/info?user_id=user123' \\
|
||||
--header 'Authorization: Bearer sk-1234'
|
||||
```
|
||||
"""
|
||||
from litellm.proxy.proxy_server import prisma_client
|
||||
|
||||
try:
|
||||
if prisma_client is None:
|
||||
raise HTTPException(
|
||||
status_code=500,
|
||||
detail=CommonProxyErrors.db_not_connected_error.value,
|
||||
)
|
||||
|
||||
# Handle URL encoding for + characters
|
||||
if user_id is not None and " " in user_id:
|
||||
user_id = get_user_id_from_request(request=request)
|
||||
|
||||
# Default to self-lookup if no user_id provided
|
||||
if user_id is None:
|
||||
user_id = user_api_key_dict.user_id
|
||||
|
||||
if user_id is None:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail="user_id is required. Either pass it as a query parameter or authenticate with a user-bound key.",
|
||||
)
|
||||
|
||||
# Check access — returns the user row if allowed, None otherwise.
|
||||
# This avoids a redundant DB fetch since the access check already
|
||||
# loads the target user for team-admin verification.
|
||||
user_row = await _check_user_info_v2_access(
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
target_user_id=user_id,
|
||||
)
|
||||
|
||||
if user_row is None:
|
||||
raise HTTPException(
|
||||
status_code=404,
|
||||
detail=f"User not found: {user_id}",
|
||||
)
|
||||
|
||||
user_data = user_row.model_dump()
|
||||
|
||||
return UserInfoV2Response(
|
||||
user_id=user_data.get("user_id", user_id),
|
||||
user_email=user_data.get("user_email"),
|
||||
user_alias=user_data.get("user_alias"),
|
||||
user_role=user_data.get("user_role"),
|
||||
spend=user_data.get("spend", 0.0),
|
||||
max_budget=user_data.get("max_budget"),
|
||||
models=user_data.get("models") or [],
|
||||
budget_duration=user_data.get("budget_duration"),
|
||||
budget_reset_at=user_data.get("budget_reset_at"),
|
||||
metadata=user_data.get("metadata"),
|
||||
created_at=user_data.get("created_at"),
|
||||
updated_at=user_data.get("updated_at"),
|
||||
sso_user_id=user_data.get("sso_user_id"),
|
||||
teams=user_data.get("teams") or [],
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.exception(
|
||||
"litellm.proxy.proxy_server.user_info_v2(): Exception occured - {}".format(
|
||||
str(e)
|
||||
)
|
||||
)
|
||||
raise handle_exception_on_proxy(e)
|
||||
|
||||
|
||||
async def _get_user_info_for_proxy_admin(user_api_key_dict: UserAPIKeyAuth):
|
||||
"""
|
||||
Admin UI Endpoint - Returns All Teams and Keys when Proxy Admin is querying
|
||||
|
|
|
|||
|
|
@ -908,6 +908,11 @@ async def _check_team_key_limits(
|
|||
keys = await prisma_client.db.litellm_verificationtoken.find_many(
|
||||
where={"team_id": team_table.team_id},
|
||||
)
|
||||
# Exclude the key being updated to avoid double-counting its limits.
|
||||
# key.token is the SHA-256 hash stored in DB; data.key is the raw key string.
|
||||
if isinstance(data, UpdateKeyRequest):
|
||||
hashed_key = hash_token(data.key)
|
||||
keys = [key for key in keys if key.token != hashed_key]
|
||||
check_team_key_model_specific_limits(
|
||||
keys=keys,
|
||||
team_table=team_table,
|
||||
|
|
@ -1062,6 +1067,11 @@ async def _check_org_key_limits(
|
|||
keys = await prisma_client.db.litellm_verificationtoken.find_many(
|
||||
where={"organization_id": org_table.organization_id},
|
||||
)
|
||||
# Exclude the key being updated to avoid double-counting its limits.
|
||||
# key.token is the SHA-256 hash stored in DB; data.key is the raw key string.
|
||||
if isinstance(data, UpdateKeyRequest):
|
||||
hashed_key = hash_token(data.key)
|
||||
keys = [key for key in keys if key.token != hashed_key]
|
||||
check_org_key_model_specific_limits(
|
||||
keys=keys,
|
||||
org_table=org_table,
|
||||
|
|
@ -1776,17 +1786,152 @@ async def _validate_mcp_servers_for_key_update(
|
|||
user_api_key_cache=user_api_key_cache,
|
||||
check_db_only=True,
|
||||
)
|
||||
object_permission_dict = (
|
||||
data.object_permission.model_dump()
|
||||
if hasattr(data.object_permission, "model_dump")
|
||||
else data.object_permission
|
||||
)
|
||||
object_permission_dict: Optional[dict] = None
|
||||
if data.object_permission is not None:
|
||||
object_permission_dict = (
|
||||
data.object_permission.model_dump()
|
||||
if hasattr(data.object_permission, "model_dump")
|
||||
else dict(data.object_permission) # type: ignore[arg-type]
|
||||
)
|
||||
await validate_key_mcp_servers_against_team(
|
||||
object_permission=object_permission_dict,
|
||||
team_obj=effective_team_obj,
|
||||
)
|
||||
|
||||
|
||||
async def _validate_update_key_data(
|
||||
data: UpdateKeyRequest,
|
||||
existing_key_row: Any,
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
llm_router: Any,
|
||||
premium_user: bool,
|
||||
prisma_client: Any,
|
||||
user_api_key_cache: Any,
|
||||
) -> None:
|
||||
"""Validate permissions and constraints for key update."""
|
||||
# sanity check - prevent non-proxy admin user from updating key to belong to a different user
|
||||
if (
|
||||
data.user_id is not None
|
||||
and data.user_id != existing_key_row.user_id
|
||||
and user_api_key_dict.user_role != LitellmUserRoles.PROXY_ADMIN.value
|
||||
):
|
||||
raise HTTPException(
|
||||
status_code=403,
|
||||
detail=f"User={data.user_id} is not allowed to update key={data.key} to belong to user={existing_key_row.user_id}",
|
||||
)
|
||||
|
||||
common_key_access_checks(
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
data=data,
|
||||
user_id=existing_key_row.user_id,
|
||||
llm_router=llm_router,
|
||||
premium_user=premium_user,
|
||||
)
|
||||
|
||||
await TeamMemberPermissionChecks.can_team_member_execute_key_management_endpoint(
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
route=KeyManagementRoutes.KEY_UPDATE,
|
||||
prisma_client=prisma_client,
|
||||
existing_key_row=existing_key_row,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
)
|
||||
|
||||
# Check team limits if key has a team_id (from request or existing key)
|
||||
team_obj: Optional[LiteLLM_TeamTableCachedObj] = None
|
||||
_team_id_to_check = data.team_id or getattr(
|
||||
existing_key_row, "team_id", None
|
||||
)
|
||||
if _team_id_to_check is not None:
|
||||
team_obj = await get_team_object(
|
||||
team_id=_team_id_to_check,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
check_db_only=True,
|
||||
)
|
||||
|
||||
if team_obj is not None:
|
||||
await _check_team_key_limits(
|
||||
team_table=team_obj,
|
||||
data=data,
|
||||
prisma_client=prisma_client,
|
||||
)
|
||||
|
||||
# Validate key against project limits if project_id is being set
|
||||
_project_id_to_check = getattr(data, "project_id", None) or getattr(
|
||||
existing_key_row, "project_id", None
|
||||
)
|
||||
if _project_id_to_check is not None and (
|
||||
data.models is not None or data.max_budget is not None
|
||||
):
|
||||
await _check_project_key_limits(
|
||||
project_id=_project_id_to_check,
|
||||
data=data,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
)
|
||||
|
||||
# Check org key limits only when throughput-related fields or organization_id change
|
||||
_org_id_to_check = data.organization_id or getattr(
|
||||
existing_key_row, "organization_id", None
|
||||
)
|
||||
_throughput_fields_changed = (
|
||||
data.organization_id is not None
|
||||
or data.tpm_limit is not None
|
||||
or data.rpm_limit is not None
|
||||
or data.tpm_limit_type is not None
|
||||
or data.rpm_limit_type is not None
|
||||
)
|
||||
if _org_id_to_check is not None and _throughput_fields_changed:
|
||||
org_table = await get_org_object(
|
||||
org_id=_org_id_to_check,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
prisma_client=prisma_client,
|
||||
)
|
||||
if org_table is None:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail=f"Organization not found for organization_id={_org_id_to_check}",
|
||||
)
|
||||
await _check_org_key_limits(
|
||||
org_table=org_table,
|
||||
data=data,
|
||||
prisma_client=prisma_client,
|
||||
)
|
||||
|
||||
# if team change - check if this is possible
|
||||
if is_different_team(data=data, existing_key_row=existing_key_row):
|
||||
if llm_router is None:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail={
|
||||
"error": "LLM router not found. Please set it up by passing in a valid config.yaml or adding models via the UI."
|
||||
},
|
||||
)
|
||||
if team_obj is None:
|
||||
raise HTTPException(
|
||||
status_code=500,
|
||||
detail={
|
||||
"error": "Team object not found for team change validation"
|
||||
},
|
||||
)
|
||||
await validate_key_team_change(
|
||||
key=existing_key_row,
|
||||
team=team_obj,
|
||||
change_initiated_by=user_api_key_dict,
|
||||
llm_router=llm_router,
|
||||
)
|
||||
|
||||
# Validate MCP servers in object_permission against the effective team
|
||||
if data.object_permission is not None:
|
||||
await _validate_mcp_servers_for_key_update(
|
||||
data=data,
|
||||
team_obj=team_obj,
|
||||
existing_key_row=existing_key_row,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
)
|
||||
|
||||
|
||||
@router.post(
|
||||
"/key/update", tags=["key management"], dependencies=[Depends(user_api_key_auth)]
|
||||
)
|
||||
|
|
@ -1809,6 +1954,7 @@ async def update_key_fn(
|
|||
- user_id: Optional[str] - User ID associated with key
|
||||
- team_id: Optional[str] - Team ID associated with key
|
||||
- agent_id: Optional[str] - The agent id associated with the key.
|
||||
- organization_id: Optional[str] - The organization id of the key.
|
||||
- budget_id: Optional[str] - The budget id associated with the key. Created by calling `/budget/new`.
|
||||
- models: Optional[list] - Model_name's a user is allowed to call
|
||||
- tags: Optional[List[str]] - Tags for organizing keys (Enterprise only)
|
||||
|
|
@ -1900,101 +2046,16 @@ async def update_key_fn(
|
|||
detail={"error": f"Team not found, passed team_id={data.team_id}"},
|
||||
)
|
||||
|
||||
## sanity check - prevent non-proxy admin user from updating key to belong to a different user
|
||||
if (
|
||||
data.user_id is not None
|
||||
and data.user_id != existing_key_row.user_id
|
||||
and user_api_key_dict.user_role != LitellmUserRoles.PROXY_ADMIN.value
|
||||
):
|
||||
raise HTTPException(
|
||||
status_code=403,
|
||||
detail=f"User={data.user_id} is not allowed to update key={key} to belong to user={existing_key_row.user_id}",
|
||||
)
|
||||
|
||||
common_key_access_checks(
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
await _validate_update_key_data(
|
||||
data=data,
|
||||
user_id=existing_key_row.user_id,
|
||||
existing_key_row=existing_key_row,
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
llm_router=llm_router,
|
||||
premium_user=premium_user,
|
||||
)
|
||||
|
||||
# check if user has permission to update key
|
||||
await TeamMemberPermissionChecks.can_team_member_execute_key_management_endpoint(
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
route=KeyManagementRoutes.KEY_UPDATE,
|
||||
prisma_client=prisma_client,
|
||||
existing_key_row=existing_key_row,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
)
|
||||
|
||||
# Only check team limits if key has a team_id
|
||||
team_obj: Optional[LiteLLM_TeamTableCachedObj] = None
|
||||
if data.team_id is not None:
|
||||
team_obj = await get_team_object(
|
||||
team_id=data.team_id,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
check_db_only=True,
|
||||
)
|
||||
|
||||
if team_obj is not None:
|
||||
await _check_team_key_limits(
|
||||
team_table=team_obj,
|
||||
data=data,
|
||||
prisma_client=prisma_client,
|
||||
)
|
||||
|
||||
# Validate key against project limits if project_id is being set
|
||||
_project_id_to_check = getattr(data, "project_id", None) or getattr(
|
||||
existing_key_row, "project_id", None
|
||||
)
|
||||
if _project_id_to_check is not None and (
|
||||
data.models is not None or data.max_budget is not None
|
||||
):
|
||||
await _check_project_key_limits(
|
||||
project_id=_project_id_to_check,
|
||||
data=data,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
)
|
||||
|
||||
# if team change - check if this is possible
|
||||
if is_different_team(data=data, existing_key_row=existing_key_row):
|
||||
if llm_router is None:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail={
|
||||
"error": "LLM router not found. Please set it up by passing in a valid config.yaml or adding models via the UI."
|
||||
},
|
||||
)
|
||||
# team_obj should be set since is_different_team() returns True only when data.team_id is not None
|
||||
if team_obj is None:
|
||||
raise HTTPException(
|
||||
status_code=500,
|
||||
detail={
|
||||
"error": "Team object not found for team change validation"
|
||||
},
|
||||
)
|
||||
await validate_key_team_change(
|
||||
key=existing_key_row,
|
||||
team=team_obj,
|
||||
change_initiated_by=user_api_key_dict,
|
||||
llm_router=llm_router,
|
||||
)
|
||||
|
||||
# Set Management Endpoint Metadata Fields
|
||||
|
||||
# Validate MCP servers in object_permission against the effective team
|
||||
if data.object_permission is not None:
|
||||
await _validate_mcp_servers_for_key_update(
|
||||
data=data,
|
||||
team_obj=team_obj,
|
||||
existing_key_row=existing_key_row,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
)
|
||||
|
||||
non_default_values = await prepare_key_update_data(
|
||||
data=data, existing_key_row=existing_key_row
|
||||
)
|
||||
|
|
|
|||
|
|
@ -1185,9 +1185,8 @@ async def update_public_model_groups(
|
|||
},
|
||||
)
|
||||
|
||||
litellm.public_model_groups = request.model_groups
|
||||
|
||||
# Load existing config
|
||||
# Load existing config first (this may overwrite in-memory litellm settings
|
||||
# from DB values via _update_config_from_db), so set the in-memory value AFTER
|
||||
config = await proxy_config.get_config()
|
||||
|
||||
# Update config with new settings
|
||||
|
|
@ -1199,6 +1198,10 @@ async def update_public_model_groups(
|
|||
# Save the updated config
|
||||
await proxy_config.save_config(new_config=config)
|
||||
|
||||
# Set in-memory value AFTER get_config() and save_config() to avoid
|
||||
# get_config() overwriting with stale DB value
|
||||
litellm.public_model_groups = request.model_groups
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
f"Updated public model groups to: {request.model_groups} by user: {user_api_key_dict.user_id}"
|
||||
)
|
||||
|
|
@ -1252,9 +1255,8 @@ async def update_useful_links(
|
|||
},
|
||||
)
|
||||
|
||||
litellm.public_model_groups_links = request.useful_links
|
||||
|
||||
# Load existing config
|
||||
# Load existing config first (this may overwrite in-memory litellm settings
|
||||
# from DB values via _update_config_from_db), so set the in-memory value AFTER
|
||||
config = await proxy_config.get_config()
|
||||
|
||||
# Update config with new settings
|
||||
|
|
@ -1266,6 +1268,10 @@ async def update_useful_links(
|
|||
# Save the updated config
|
||||
await proxy_config.save_config(new_config=config)
|
||||
|
||||
# Set in-memory value AFTER get_config() and save_config() to avoid
|
||||
# get_config() overwriting with stale DB value
|
||||
litellm.public_model_groups_links = request.useful_links
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
f"Updated useful links to: {request.useful_links} by user: {user_api_key_dict.user_id}"
|
||||
)
|
||||
|
|
|
|||
|
|
@ -17,7 +17,9 @@ import secrets
|
|||
from copy import deepcopy
|
||||
from typing import TYPE_CHECKING, Any, Dict, List, Literal, Optional, Tuple, Union, cast
|
||||
|
||||
import httpx
|
||||
if TYPE_CHECKING:
|
||||
import httpx
|
||||
|
||||
import jwt
|
||||
from fastapi import APIRouter, Depends, HTTPException, Request, status
|
||||
from fastapi.responses import RedirectResponse
|
||||
|
|
@ -2765,6 +2767,69 @@ class SSOAuthenticationHandler:
|
|||
|
||||
return code_verifier, code_challenge
|
||||
|
||||
@staticmethod
|
||||
def _validate_token_response(response: "httpx.Response") -> dict:
|
||||
"""
|
||||
Parse and validate the token endpoint response.
|
||||
|
||||
Ensures the response is valid JSON, a dict, and contains a non-null
|
||||
access_token string. Raises ProxyException on any validation failure.
|
||||
"""
|
||||
try:
|
||||
token_response_raw = response.json()
|
||||
except Exception as json_err:
|
||||
verbose_proxy_logger.error(
|
||||
"Failed to parse token response as JSON: %s. Body: %s",
|
||||
json_err,
|
||||
response.text[:500],
|
||||
)
|
||||
raise ProxyException(
|
||||
message=f"Token endpoint returned invalid JSON: {json_err}",
|
||||
type=ProxyErrorTypes.auth_error,
|
||||
param="token_exchange",
|
||||
code=status.HTTP_401_UNAUTHORIZED,
|
||||
)
|
||||
|
||||
if not isinstance(token_response_raw, dict):
|
||||
verbose_proxy_logger.error(
|
||||
"Token endpoint returned non-dict JSON (type=%s). Body: %s",
|
||||
type(token_response_raw).__name__,
|
||||
response.text[:500],
|
||||
)
|
||||
raise ProxyException(
|
||||
message=(
|
||||
f"Token endpoint returned unexpected response format "
|
||||
f"(expected JSON object, got {type(token_response_raw).__name__})"
|
||||
),
|
||||
type=ProxyErrorTypes.auth_error,
|
||||
param="token_exchange",
|
||||
code=status.HTTP_401_UNAUTHORIZED,
|
||||
)
|
||||
token_response: dict = token_response_raw
|
||||
|
||||
access_token_val = token_response.get("access_token")
|
||||
if not isinstance(access_token_val, str) or not access_token_val:
|
||||
error = token_response.get("error")
|
||||
error_desc = token_response.get("error_description", "")
|
||||
if error:
|
||||
detail = f"{error} - {error_desc}" if error_desc else error
|
||||
else:
|
||||
detail = (
|
||||
"token endpoint returned HTTP 200 but no access_token "
|
||||
f"(response keys: {sorted(token_response.keys())})"
|
||||
)
|
||||
verbose_proxy_logger.error(
|
||||
"Token response missing or null access_token. detail=%s", detail
|
||||
)
|
||||
raise ProxyException(
|
||||
message=f"Token exchange failed: {detail}",
|
||||
type=ProxyErrorTypes.auth_error,
|
||||
param="token_exchange",
|
||||
code=status.HTTP_401_UNAUTHORIZED,
|
||||
)
|
||||
|
||||
return token_response
|
||||
|
||||
@staticmethod
|
||||
async def _pkce_token_exchange(
|
||||
authorization_code: str,
|
||||
|
|
@ -2801,20 +2866,19 @@ class SSOAuthenticationHandler:
|
|||
if redirect_url:
|
||||
token_data["redirect_uri"] = redirect_url
|
||||
|
||||
post_kwargs: Dict[str, Any] = {
|
||||
"data": token_data,
|
||||
"headers": {
|
||||
**additional_headers,
|
||||
"Content-Type": "application/x-www-form-urlencoded", # must not be overridden
|
||||
"Accept": "application/json",
|
||||
},
|
||||
"timeout": 30.0,
|
||||
request_headers = {
|
||||
**additional_headers,
|
||||
"Content-Type": "application/x-www-form-urlencoded", # must not be overridden
|
||||
"Accept": "application/json",
|
||||
}
|
||||
|
||||
if not include_client_id:
|
||||
# Use Basic Auth only when a secret is available; public PKCE clients omit it.
|
||||
if client_secret:
|
||||
post_kwargs["auth"] = httpx.BasicAuth(client_id, client_secret)
|
||||
credentials = base64.b64encode(
|
||||
f"{client_id}:{client_secret}".encode()
|
||||
).decode()
|
||||
request_headers["Authorization"] = f"Basic {credentials}"
|
||||
else:
|
||||
token_data["client_id"] = client_id
|
||||
else:
|
||||
|
|
@ -2822,27 +2886,27 @@ class SSOAuthenticationHandler:
|
|||
if client_secret:
|
||||
token_data["client_secret"] = client_secret
|
||||
|
||||
# The try/except is INSIDE the async with so that TLS teardown exceptions
|
||||
# from __aexit__ propagate as-is and are NOT mis-labelled as "Token endpoint
|
||||
# request failed". httpx buffers the full response body before __aexit__,
|
||||
# so status_code / text / json() remain valid after the context exits.
|
||||
async with httpx.AsyncClient() as http_client:
|
||||
try:
|
||||
response = await http_client.post(token_endpoint, **post_kwargs)
|
||||
except Exception as exc:
|
||||
# Catch network-level errors (SSL, DNS, TCP, timeout, etc.) and
|
||||
# wrap them as a clean ProxyException rather than leaking raw
|
||||
# httpx or OS exceptions to callers.
|
||||
verbose_proxy_logger.error("PKCE token endpoint unreachable: %s", exc)
|
||||
raise ProxyException(
|
||||
message=f"Token endpoint request failed: {exc}",
|
||||
type=ProxyErrorTypes.auth_error,
|
||||
param="token_exchange",
|
||||
code=status.HTTP_401_UNAUTHORIZED,
|
||||
) from exc
|
||||
|
||||
# Response processing outside the async with — httpx buffers the full
|
||||
# response body so status_code / text / json() remain valid after __aexit__.
|
||||
http_client = get_async_httpx_client(
|
||||
llm_provider=httpxSpecialProvider.SSO_HANDLER
|
||||
)
|
||||
try:
|
||||
response = await http_client.post(
|
||||
url=token_endpoint,
|
||||
data=token_data,
|
||||
headers=request_headers,
|
||||
timeout=30.0,
|
||||
)
|
||||
except Exception as exc:
|
||||
# Catch network-level errors (SSL, DNS, TCP, timeout, etc.) and
|
||||
# wrap them as a clean ProxyException rather than leaking raw
|
||||
# httpx or OS exceptions to callers.
|
||||
verbose_proxy_logger.error("PKCE token endpoint unreachable: %s", exc)
|
||||
raise ProxyException(
|
||||
message=f"Token endpoint request failed: {exc}",
|
||||
type=ProxyErrorTypes.auth_error,
|
||||
param="token_exchange",
|
||||
code=status.HTTP_401_UNAUTHORIZED,
|
||||
) from exc
|
||||
if response.status_code != 200:
|
||||
verbose_proxy_logger.error(
|
||||
"PKCE token exchange failed. status=%s body=%s",
|
||||
|
|
@ -2856,63 +2920,7 @@ class SSOAuthenticationHandler:
|
|||
code=status.HTTP_401_UNAUTHORIZED,
|
||||
)
|
||||
|
||||
try:
|
||||
token_response_raw = response.json()
|
||||
except Exception as json_err:
|
||||
verbose_proxy_logger.error(
|
||||
"Failed to parse token response as JSON: %s. Body: %s",
|
||||
json_err,
|
||||
response.text[:500],
|
||||
)
|
||||
raise ProxyException(
|
||||
message=f"Token endpoint returned invalid JSON: {json_err}",
|
||||
type=ProxyErrorTypes.auth_error,
|
||||
param="token_exchange",
|
||||
code=status.HTTP_401_UNAUTHORIZED,
|
||||
)
|
||||
|
||||
# Guard against HTTP 200 with body `null` — response.json() returns Python None
|
||||
# in that case, and calling .get() on None raises AttributeError.
|
||||
if not isinstance(token_response_raw, dict):
|
||||
verbose_proxy_logger.error(
|
||||
"Token endpoint returned non-dict JSON (type=%s). Body: %s",
|
||||
type(token_response_raw).__name__,
|
||||
response.text[:500],
|
||||
)
|
||||
raise ProxyException(
|
||||
message=(
|
||||
f"Token endpoint returned unexpected response format "
|
||||
f"(expected JSON object, got {type(token_response_raw).__name__})"
|
||||
),
|
||||
type=ProxyErrorTypes.auth_error,
|
||||
param="token_exchange",
|
||||
code=status.HTTP_401_UNAUTHORIZED,
|
||||
)
|
||||
token_response: dict = token_response_raw
|
||||
|
||||
# Some providers return HTTP 200 with an error body (e.g. expired code, replay attack).
|
||||
# Also guard against JSON `null` for access_token — it passes key-existence checks
|
||||
# but would produce a "Bearer None" Authorization header downstream.
|
||||
access_token_val = token_response.get("access_token")
|
||||
if not isinstance(access_token_val, str) or not access_token_val:
|
||||
error = token_response.get("error")
|
||||
error_desc = token_response.get("error_description", "")
|
||||
if error:
|
||||
detail = f"{error} - {error_desc}" if error_desc else error
|
||||
else:
|
||||
detail = (
|
||||
"token endpoint returned HTTP 200 but no access_token "
|
||||
f"(response keys: {sorted(token_response.keys())})"
|
||||
)
|
||||
verbose_proxy_logger.error(
|
||||
"Token response missing or null access_token. detail=%s", detail
|
||||
)
|
||||
raise ProxyException(
|
||||
message=f"Token exchange failed: {detail}",
|
||||
type=ProxyErrorTypes.auth_error,
|
||||
param="token_exchange",
|
||||
code=status.HTTP_401_UNAUTHORIZED,
|
||||
)
|
||||
token_response = SSOAuthenticationHandler._validate_token_response(response)
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
"PKCE token exchange successful. id_token_present=%s",
|
||||
|
|
@ -2970,41 +2978,42 @@ class SSOAuthenticationHandler:
|
|||
|
||||
if userinfo_endpoint:
|
||||
try:
|
||||
async with httpx.AsyncClient() as client:
|
||||
resp = await client.get(
|
||||
userinfo_endpoint,
|
||||
headers={
|
||||
**additional_headers,
|
||||
"Authorization": f"Bearer {access_token}", # must not be overridden
|
||||
},
|
||||
timeout=30.0,
|
||||
)
|
||||
if resp.status_code == 200:
|
||||
try:
|
||||
userinfo_raw = resp.json()
|
||||
if not userinfo_raw:
|
||||
# JSON null (None) or empty dict ({}) — no identity claims.
|
||||
# Treat as failure so id_token fallback can be attempted.
|
||||
verbose_proxy_logger.warning(
|
||||
"Userinfo endpoint returned an empty or null response "
|
||||
"(type=%s); treating as failure and attempting id_token fallback. "
|
||||
"Check your provider's userinfo endpoint configuration.",
|
||||
type(userinfo_raw).__name__,
|
||||
)
|
||||
userinfo = None
|
||||
else:
|
||||
userinfo = userinfo_raw
|
||||
except Exception as json_err:
|
||||
client = get_async_httpx_client(
|
||||
llm_provider=httpxSpecialProvider.SSO_HANDLER
|
||||
)
|
||||
resp = await client.get(
|
||||
url=userinfo_endpoint,
|
||||
headers={
|
||||
**additional_headers,
|
||||
"Authorization": f"Bearer {access_token}", # must not be overridden
|
||||
},
|
||||
)
|
||||
if resp.status_code == 200:
|
||||
try:
|
||||
userinfo_raw = resp.json()
|
||||
if not userinfo_raw:
|
||||
# JSON null (None) or empty dict ({}) — no identity claims.
|
||||
# Treat as failure so id_token fallback can be attempted.
|
||||
verbose_proxy_logger.warning(
|
||||
"Userinfo endpoint returned non-JSON response (status 200): %s",
|
||||
json_err,
|
||||
"Userinfo endpoint returned an empty or null response "
|
||||
"(type=%s); treating as failure and attempting id_token fallback. "
|
||||
"Check your provider's userinfo endpoint configuration.",
|
||||
type(userinfo_raw).__name__,
|
||||
)
|
||||
else:
|
||||
userinfo = None
|
||||
else:
|
||||
userinfo = userinfo_raw
|
||||
except Exception as json_err:
|
||||
verbose_proxy_logger.warning(
|
||||
"Userinfo endpoint returned %s (body: %s), falling back to id_token",
|
||||
resp.status_code,
|
||||
resp.text[:500],
|
||||
"Userinfo endpoint returned non-JSON response (status 200): %s",
|
||||
json_err,
|
||||
)
|
||||
else:
|
||||
verbose_proxy_logger.warning(
|
||||
"Userinfo endpoint returned %s (body: %s), falling back to id_token",
|
||||
resp.status_code,
|
||||
resp.text[:500],
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.warning(
|
||||
"Userinfo endpoint error: %s, falling back to id_token", e
|
||||
|
|
|
|||
|
|
@ -214,6 +214,7 @@ from litellm.constants import (
|
|||
DEFAULT_MODEL_CREATED_AT_TIME,
|
||||
LITELLM_PROXY_ADMIN_NAME,
|
||||
PROMETHEUS_FALLBACK_STATS_SEND_TIME_HOURS,
|
||||
PROXY_BATCH_POLLING_ENABLED,
|
||||
PROXY_BATCH_POLLING_INTERVAL,
|
||||
PROXY_BATCH_WRITE_AT,
|
||||
PROXY_BUDGET_RESCHEDULER_MAX_TIME,
|
||||
|
|
@ -260,7 +261,6 @@ from litellm.proxy.anthropic_endpoints.claude_code_endpoints import (
|
|||
claude_code_marketplace_router,
|
||||
)
|
||||
from litellm.proxy.anthropic_endpoints.endpoints import router as anthropic_router
|
||||
from litellm.proxy.realtime_endpoints.endpoints import router as webrtc_router
|
||||
from litellm.proxy.anthropic_endpoints.skills_endpoints import (
|
||||
router as anthropic_skills_router,
|
||||
)
|
||||
|
|
@ -471,6 +471,7 @@ from litellm.proxy.policy_engine.policy_resolve_endpoints import (
|
|||
from litellm.proxy.prompts.prompt_endpoints import router as prompts_router
|
||||
from litellm.proxy.public_endpoints import router as public_endpoints_router
|
||||
from litellm.proxy.rag_endpoints.endpoints import router as rag_router
|
||||
from litellm.proxy.realtime_endpoints.endpoints import router as webrtc_router
|
||||
from litellm.proxy.rerank_endpoints.endpoints import router as rerank_router
|
||||
from litellm.proxy.response_api_endpoints.endpoints import router as response_router
|
||||
from litellm.proxy.route_llm_request import route_request
|
||||
|
|
@ -6069,7 +6070,7 @@ class ProxyStartupEvent:
|
|||
"Invalid maximum_spend_logs_retention_interval value"
|
||||
)
|
||||
### CHECK BATCH COST ###
|
||||
if llm_router is not None:
|
||||
if llm_router is not None and PROXY_BATCH_POLLING_ENABLED:
|
||||
try:
|
||||
from litellm_enterprise.proxy.common_utils.check_batch_cost import (
|
||||
CheckBatchCost,
|
||||
|
|
@ -6100,7 +6101,7 @@ class ProxyStartupEvent:
|
|||
pass
|
||||
|
||||
### CHECK RESPONSES COST ###
|
||||
if llm_router is not None:
|
||||
if llm_router is not None and PROXY_BATCH_POLLING_ENABLED:
|
||||
try:
|
||||
from litellm_enterprise.proxy.common_utils.check_responses_cost import (
|
||||
CheckResponsesCost,
|
||||
|
|
|
|||
|
|
@ -181,7 +181,7 @@ async def create_realtime_client_secret(
|
|||
upstream_resp.status_code,
|
||||
upstream_resp.text,
|
||||
)
|
||||
return Response(
|
||||
return Response( # type: ignore[return-value]
|
||||
content=upstream_resp.content,
|
||||
status_code=upstream_resp.status_code,
|
||||
media_type="application/json",
|
||||
|
|
|
|||
|
|
@ -113,6 +113,16 @@ async def background_streaming_task( # noqa: PLR0915
|
|||
last_update_time = asyncio.get_event_loop().time()
|
||||
UPDATE_INTERVAL = 0.150 # 150ms batching interval
|
||||
|
||||
# Track the terminal event from the stream (may not be "completed")
|
||||
terminal_status = None # Will be set by response.completed/failed/incomplete/cancelled
|
||||
terminal_error = None
|
||||
_event_to_status = {
|
||||
"response.completed": "completed",
|
||||
"response.failed": "failed",
|
||||
"response.incomplete": "incomplete",
|
||||
"response.cancelled": "cancelled",
|
||||
}
|
||||
|
||||
async def flush_state_if_needed(force: bool = False) -> None:
|
||||
"""Flush accumulated state to Redis if interval elapsed or forced"""
|
||||
nonlocal state_dirty, last_update_time
|
||||
|
|
@ -131,6 +141,12 @@ async def background_streaming_task( # noqa: PLR0915
|
|||
last_update_time = current_time
|
||||
|
||||
# Handle StreamingResponse
|
||||
if not hasattr(response, "body_iterator"):
|
||||
verbose_proxy_logger.warning(
|
||||
f"background_streaming_task: response for {polling_id} has no "
|
||||
"body_iterator; this may indicate a misconfiguration or provider error"
|
||||
)
|
||||
|
||||
if hasattr(response, "body_iterator"):
|
||||
async for chunk in response.body_iterator:
|
||||
# Parse chunk
|
||||
|
|
@ -224,10 +240,23 @@ async def background_streaming_task( # noqa: PLR0915
|
|||
status="in_progress",
|
||||
)
|
||||
|
||||
elif event_type == "response.completed":
|
||||
# Response completed - extract all ResponsesAPIResponse fields
|
||||
# https://platform.openai.com/docs/api-reference/responses-streaming/response-completed
|
||||
elif event_type in (
|
||||
"response.completed",
|
||||
"response.failed",
|
||||
"response.incomplete",
|
||||
"response.cancelled",
|
||||
):
|
||||
# Terminal event - extract all ResponsesAPIResponse fields
|
||||
# https://platform.openai.com/docs/api-reference/responses-streaming
|
||||
response_data = event.get("response", {})
|
||||
terminal_status = response_data.get(
|
||||
"status",
|
||||
_event_to_status.get(event_type, "completed"),
|
||||
)
|
||||
|
||||
# Extract error for failed responses
|
||||
if event_type == "response.failed":
|
||||
terminal_error = response_data.get("error")
|
||||
|
||||
# Core response fields
|
||||
usage_data = response_data.get("usage")
|
||||
|
|
@ -278,11 +307,14 @@ async def background_streaming_task( # noqa: PLR0915
|
|||
# Final flush to ensure all accumulated state is saved
|
||||
await flush_state_if_needed(force=True)
|
||||
|
||||
# Mark as completed with all ResponsesAPIResponse fields
|
||||
# Use the terminal status from the stream, default to "completed"
|
||||
final_status = terminal_status or "completed"
|
||||
|
||||
await polling_handler.update_state(
|
||||
polling_id=polling_id,
|
||||
status="completed",
|
||||
status=final_status,
|
||||
usage=usage_data,
|
||||
error=terminal_error,
|
||||
reasoning=reasoning_data,
|
||||
tool_choice=tool_choice_data,
|
||||
tools=tools_data,
|
||||
|
|
@ -301,7 +333,7 @@ async def background_streaming_task( # noqa: PLR0915
|
|||
)
|
||||
|
||||
verbose_proxy_logger.info(
|
||||
f"Completed background streaming for {polling_id}, output_items={len(output_items)}"
|
||||
f"Finished background streaming for {polling_id}, status={final_status}, output_items={len(output_items)}"
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
|
|
|
|||
|
|
@ -173,8 +173,21 @@ async def route_request( # noqa: PLR0915 - Complex routing function, refactorin
|
|||
"agenerate_content",
|
||||
"agenerate_content_stream",
|
||||
"allm_passthrough_route",
|
||||
"acreate_batch",
|
||||
"aretrieve_batch",
|
||||
"alist_batches",
|
||||
"afile_content",
|
||||
"afile_retrieve",
|
||||
"acreate_fine_tuning_job",
|
||||
"acancel_fine_tuning_job",
|
||||
"alist_fine_tuning_jobs",
|
||||
"aretrieve_fine_tuning_job",
|
||||
"avector_store_search",
|
||||
"avector_store_create",
|
||||
"avector_store_retrieve",
|
||||
"avector_store_list",
|
||||
"avector_store_update",
|
||||
"avector_store_delete",
|
||||
"avector_store_file_create",
|
||||
"avector_store_file_list",
|
||||
"avector_store_file_retrieve",
|
||||
|
|
@ -207,6 +220,8 @@ async def route_request( # noqa: PLR0915 - Complex routing function, refactorin
|
|||
"aget_interaction",
|
||||
"adelete_interaction",
|
||||
"acancel_interaction",
|
||||
"asend_message",
|
||||
"call_mcp_tool",
|
||||
"acancel_batch",
|
||||
"afile_delete",
|
||||
"acreate_eval",
|
||||
|
|
|
|||
|
|
@ -386,7 +386,7 @@ async def vector_store_list(
|
|||
version,
|
||||
)
|
||||
|
||||
data = {}
|
||||
data: dict = {}
|
||||
if after is not None:
|
||||
data["after"] = after
|
||||
if before is not None:
|
||||
|
|
|
|||
|
|
@ -9,7 +9,12 @@ from litellm.litellm_core_utils.get_llm_provider_logic import get_llm_provider
|
|||
from litellm.llms.base_llm.realtime.transformation import BaseRealtimeConfig
|
||||
from litellm.llms.custom_httpx.llm_http_handler import BaseLLMHTTPHandler
|
||||
from litellm.secret_managers.main import get_secret_str
|
||||
from litellm.types.realtime import RealtimeClientSecretRequest, RealtimeQueryParams
|
||||
from litellm.types.realtime import (
|
||||
RealtimeClientSecretRequest,
|
||||
RealtimeExpiresAfter,
|
||||
RealtimeQueryParams,
|
||||
RealtimeSessionConfig,
|
||||
)
|
||||
from litellm.types.router import GenericLiteLLMParams
|
||||
from litellm.types.utils import LlmProviders
|
||||
from litellm.utils import ProviderConfigManager
|
||||
|
|
@ -100,8 +105,8 @@ async def acreate_realtime_client_secret(
|
|||
):
|
||||
req = RealtimeClientSecretRequest(
|
||||
model=model,
|
||||
session=session,
|
||||
expires_after=expires_after,
|
||||
session=RealtimeSessionConfig(**session) if session else None,
|
||||
expires_after=RealtimeExpiresAfter(**expires_after) if expires_after else None,
|
||||
)
|
||||
model_name = (
|
||||
(req.session.model if req.session is not None else None)
|
||||
|
|
|
|||
|
|
@ -410,11 +410,12 @@ class LiteLLMCompletionResponsesConfig:
|
|||
else getattr(new_msg, "role", None)
|
||||
)
|
||||
if new_role == "assistant":
|
||||
new_tcs = (
|
||||
_raw_tcs = (
|
||||
new_msg.get("tool_calls")
|
||||
if isinstance(new_msg, dict)
|
||||
else getattr(new_msg, "tool_calls", None)
|
||||
) or []
|
||||
)
|
||||
new_tcs: list = _raw_tcs if isinstance(_raw_tcs, list) else []
|
||||
for tc in new_tcs:
|
||||
LiteLLMCompletionResponsesConfig._add_tool_call_to_assistant(
|
||||
last_msg, tc
|
||||
|
|
|
|||
|
|
@ -4846,10 +4846,6 @@ class Router:
|
|||
"generate_content_stream",
|
||||
"vector_store_search",
|
||||
"vector_store_create",
|
||||
"vector_store_retrieve",
|
||||
"vector_store_list",
|
||||
"vector_store_update",
|
||||
"vector_store_delete",
|
||||
"ocr",
|
||||
"search",
|
||||
"video_generation",
|
||||
|
|
@ -4874,6 +4870,28 @@ class Router:
|
|||
|
||||
return sync_wrapper
|
||||
|
||||
if call_type in (
|
||||
"vector_store_retrieve",
|
||||
"vector_store_list",
|
||||
"vector_store_update",
|
||||
"vector_store_delete",
|
||||
):
|
||||
|
||||
def vector_store_sync_wrapper(
|
||||
custom_llm_provider: Optional[str] = None,
|
||||
client: Optional[Any] = None,
|
||||
**kwargs,
|
||||
):
|
||||
if custom_llm_provider and "custom_llm_provider" not in kwargs:
|
||||
kwargs["custom_llm_provider"] = custom_llm_provider
|
||||
if kwargs.get("model"):
|
||||
return self._generic_api_call_with_fallbacks(
|
||||
original_function=original_function, **kwargs
|
||||
)
|
||||
return original_function(**kwargs)
|
||||
|
||||
return vector_store_sync_wrapper
|
||||
|
||||
if call_type in (
|
||||
"vector_store_file_create",
|
||||
"vector_store_file_list",
|
||||
|
|
|
|||
|
|
@ -19,11 +19,11 @@ if TYPE_CHECKING:
|
|||
GenerateContentRequestParametersDict = _genai_types._GenerateContentParametersDict
|
||||
ToolConfigDict = _genai_types.ToolConfigDict
|
||||
|
||||
class GenerateContentRequestDict(GenerateContentRequestParametersDict): # type: ignore[misc]
|
||||
class GenerateContentRequestDict(GenerateContentRequestParametersDict): # type: ignore[misc, valid-type]
|
||||
generationConfig: Optional[Any]
|
||||
tools: Optional[ToolConfigDict] # type: ignore[assignment]
|
||||
tools: Optional[ToolConfigDict] # type: ignore[assignment, valid-type]
|
||||
|
||||
class GenerateContentResponse(GoogleGenAIGenerateContentResponse, BaseLiteLLMOpenAIResponseObject): # type: ignore[misc]
|
||||
class GenerateContentResponse(GoogleGenAIGenerateContentResponse, BaseLiteLLMOpenAIResponseObject): # type: ignore[misc, valid-type]
|
||||
_hidden_params: dict = {}
|
||||
pass
|
||||
|
||||
|
|
|
|||
|
|
@ -1052,6 +1052,14 @@ OpenAIImageGenerationOptionalParams = Literal[
|
|||
"size",
|
||||
"style",
|
||||
"user",
|
||||
"seed",
|
||||
"safety_tolerance",
|
||||
"prompt_upsampling",
|
||||
"raw",
|
||||
"num_images",
|
||||
"image_url",
|
||||
"image_prompt_strength",
|
||||
"aspect_ratio",
|
||||
]
|
||||
|
||||
OpenAIImageEditOptionalParams = Literal[
|
||||
|
|
|
|||
|
|
@ -1663,7 +1663,7 @@ class StreamingChoices(OpenAIObject):
|
|||
if finish_reason:
|
||||
self.finish_reason = map_finish_reason(finish_reason)
|
||||
else:
|
||||
self.finish_reason = None
|
||||
self.finish_reason = None # type: ignore[assignment]
|
||||
self.index = index
|
||||
if delta is not None:
|
||||
if isinstance(delta, Delta):
|
||||
|
|
|
|||
|
|
@ -8141,6 +8141,8 @@ class ProviderConfigManager:
|
|||
raise ValueError(f"Provider {provider.value} not found")
|
||||
return create_config_class(provider_config)()
|
||||
|
||||
return None
|
||||
|
||||
@staticmethod
|
||||
def get_provider_embedding_config(
|
||||
model: str,
|
||||
|
|
|
|||
|
|
@ -22083,6 +22083,7 @@
|
|||
"output_cost_per_token": 3e-06,
|
||||
"source": "https://platform.moonshot.ai/docs/guide/kimi-k2-5-quickstart",
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_video_input": true,
|
||||
"supports_vision": true
|
||||
|
|
@ -22166,6 +22167,7 @@
|
|||
"output_cost_per_token": 2.5e-06,
|
||||
"source": "https://platform.moonshot.ai/docs/pricing/chat#generation-model-kimi-k2",
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_web_search": true
|
||||
},
|
||||
|
|
@ -22180,6 +22182,7 @@
|
|||
"output_cost_per_token": 8e-06,
|
||||
"source": "https://platform.moonshot.ai/docs/pricing/chat#generation-model-kimi-k2",
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_web_search": true
|
||||
},
|
||||
|
|
|
|||
|
|
@ -12,7 +12,7 @@
|
|||
},
|
||||
"overrides": {
|
||||
"glob": ">=11.1.0",
|
||||
"tar": ">=7.5.10",
|
||||
"tar": ">=7.5.11",
|
||||
"minimatch": ">=10.2.4",
|
||||
"diff": ">=8.0.3",
|
||||
"@isaacs/brace-expansion": ">=5.0.1",
|
||||
|
|
@ -27,4 +27,4 @@
|
|||
"serve-static": ">=1.16.0",
|
||||
"path-to-regexp": ">=0.1.12"
|
||||
}
|
||||
}
|
||||
}
|
||||
|
|
|
|||
73
poetry.lock
generated
73
poetry.lock
generated
|
|
@ -1,4 +1,4 @@
|
|||
# This file is automatically @generated by Poetry 2.3.2 and should not be changed by hand.
|
||||
# This file is automatically @generated by Poetry 2.2.1 and should not be changed by hand.
|
||||
|
||||
[[package]]
|
||||
name = "a2a-sdk"
|
||||
|
|
@ -7,11 +7,11 @@ description = "A2A Python SDK"
|
|||
optional = false
|
||||
python-versions = ">=3.10"
|
||||
groups = ["main", "proxy-dev"]
|
||||
markers = "python_version >= \"3.10\""
|
||||
files = [
|
||||
{file = "a2a_sdk-0.3.22-py3-none-any.whl", hash = "sha256:b98701135bb90b0ff85d35f31533b6b7a299bf810658c1c65f3814a6c15ea385"},
|
||||
{file = "a2a_sdk-0.3.22.tar.gz", hash = "sha256:77a5694bfc4f26679c11b70c7f1062522206d430b34bc1215cfbb1eba67b7e7d"},
|
||||
]
|
||||
markers = {main = "python_version >= \"3.10\" and extra == \"extra-proxy\"", proxy-dev = "python_version >= \"3.10\""}
|
||||
|
||||
[package.dependencies]
|
||||
google-api-core = ">=1.26.0"
|
||||
|
|
@ -385,7 +385,6 @@ files = [
|
|||
{file = "azure_core-1.36.0-py3-none-any.whl", hash = "sha256:fee9923a3a753e94a259563429f3644aaf05c486d45b1215d098115102d91d3b"},
|
||||
{file = "azure_core-1.36.0.tar.gz", hash = "sha256:22e5605e6d0bf1d229726af56d9e92bc37b6e726b141a18be0b4d424131741b7"},
|
||||
]
|
||||
markers = {main = "extra == \"proxy\" or extra == \"extra-proxy\""}
|
||||
|
||||
[package.dependencies]
|
||||
requests = ">=2.21.0"
|
||||
|
|
@ -406,7 +405,6 @@ files = [
|
|||
{file = "azure_identity-1.25.1-py3-none-any.whl", hash = "sha256:e9edd720af03dff020223cd269fa3a61e8f345ea75443858273bcb44844ab651"},
|
||||
{file = "azure_identity-1.25.1.tar.gz", hash = "sha256:87ca8328883de6036443e1c37b40e8dc8fb74898240f61071e09d2e369361456"},
|
||||
]
|
||||
markers = {main = "extra == \"proxy\" or extra == \"extra-proxy\""}
|
||||
|
||||
[package.dependencies]
|
||||
azure-core = ">=1.31.0"
|
||||
|
|
@ -600,7 +598,7 @@ files = [
|
|||
{file = "cachetools-6.2.2-py3-none-any.whl", hash = "sha256:6c09c98183bf58560c97b2abfcedcbaf6a896a490f534b031b661d3723b45ace"},
|
||||
{file = "cachetools-6.2.2.tar.gz", hash = "sha256:8e6d266b25e539df852251cfd6f990b4bc3a141db73b939058d809ebd2590fc6"},
|
||||
]
|
||||
markers = {main = "python_version >= \"3.10\" and (extra == \"extra-proxy\" or extra == \"google\" or extra == \"mlflow\") or extra == \"google\" or extra == \"extra-proxy\"", proxy-dev = "python_version >= \"3.10\""}
|
||||
markers = {main = "extra == \"google\" or extra == \"extra-proxy\" or python_version >= \"3.10\"", proxy-dev = "python_version >= \"3.10\""}
|
||||
|
||||
[[package]]
|
||||
name = "certifi"
|
||||
|
|
@ -707,7 +705,7 @@ files = [
|
|||
{file = "cffi-2.0.0-cp39-cp39-win_amd64.whl", hash = "sha256:b882b3df248017dba09d6b16defe9b5c407fe32fc7c65a9c69798e6175601be9"},
|
||||
{file = "cffi-2.0.0.tar.gz", hash = "sha256:44d1b5909021139fe36001ae048dbdde8214afa20200eda0f64c068cac5d5529"},
|
||||
]
|
||||
markers = {main = "(platform_python_implementation != \"PyPy\" or extra == \"proxy\") and (python_version >= \"3.10\" or extra == \"proxy\" or extra == \"extra-proxy\") and (extra == \"proxy\" or extra == \"extra-proxy\" or extra == \"mlflow\")", dev = "platform_python_implementation != \"PyPy\"", proxy-dev = "platform_python_implementation != \"PyPy\""}
|
||||
markers = {main = "platform_python_implementation != \"PyPy\" or extra == \"proxy\"", dev = "platform_python_implementation != \"PyPy\"", proxy-dev = "platform_python_implementation != \"PyPy\""}
|
||||
|
||||
[package.dependencies]
|
||||
pycparser = {version = "*", markers = "implementation_name != \"PyPy\""}
|
||||
|
|
@ -1057,7 +1055,6 @@ files = [
|
|||
{file = "cryptography-43.0.3-pp39-pypy39_pp73-win_amd64.whl", hash = "sha256:2ce6fae5bdad59577b44e4dfed356944fbf1d925269114c28be377692643b4ff"},
|
||||
{file = "cryptography-43.0.3.tar.gz", hash = "sha256:315b9001266a492a6ff443b61238f956b214dbec9910a081ba5b6646a055a805"},
|
||||
]
|
||||
markers = {main = "python_version >= \"3.10\" and (extra == \"proxy\" or extra == \"extra-proxy\" or extra == \"mlflow\") or extra == \"proxy\" or extra == \"extra-proxy\""}
|
||||
|
||||
[package.dependencies]
|
||||
cffi = {version = ">=1.12", markers = "platform_python_implementation != \"PyPy\""}
|
||||
|
|
@ -1840,11 +1837,11 @@ description = "Google API client core library"
|
|||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
groups = ["main", "proxy-dev"]
|
||||
markers = "python_version >= \"3.14\""
|
||||
files = [
|
||||
{file = "google_api_core-2.25.2-py3-none-any.whl", hash = "sha256:e9a8f62d363dc8424a8497f4c2a47d6bcda6c16514c935629c257ab5d10210e7"},
|
||||
{file = "google_api_core-2.25.2.tar.gz", hash = "sha256:1c63aa6af0d0d5e37966f157a77f9396d820fba59f9e43e9415bc3dc5baff300"},
|
||||
]
|
||||
markers = {main = "python_version >= \"3.14\" and (extra == \"extra-proxy\" or extra == \"google\")", proxy-dev = "python_version >= \"3.14\""}
|
||||
|
||||
[package.dependencies]
|
||||
google-auth = ">=2.14.1,<3.0.0"
|
||||
|
|
@ -1872,7 +1869,7 @@ files = [
|
|||
{file = "google_api_core-2.28.1-py3-none-any.whl", hash = "sha256:4021b0f8ceb77a6fb4de6fde4502cecab45062e66ff4f2895169e0b35bc9466c"},
|
||||
{file = "google_api_core-2.28.1.tar.gz", hash = "sha256:2b405df02d68e68ce0fbc138559e6036559e685159d148ae5861013dc201baf8"},
|
||||
]
|
||||
markers = {main = "python_version < \"3.14\" and (extra == \"extra-proxy\" or extra == \"google\")", proxy-dev = "python_version >= \"3.10\" and python_version < \"3.14\""}
|
||||
markers = {main = "(python_version >= \"3.10\" or extra == \"google\" or extra == \"extra-proxy\") and python_version < \"3.14\"", proxy-dev = "python_version >= \"3.10\" and python_version < \"3.14\""}
|
||||
|
||||
[package.dependencies]
|
||||
google-auth = ">=2.14.1,<3.0.0"
|
||||
|
|
@ -1909,7 +1906,7 @@ files = [
|
|||
{file = "google_auth-2.43.0-py2.py3-none-any.whl", hash = "sha256:af628ba6fa493f75c7e9dbe9373d148ca9f4399b5ea29976519e0a3848eddd16"},
|
||||
{file = "google_auth-2.43.0.tar.gz", hash = "sha256:88228eee5fc21b62a1b5fe773ca15e67778cb07dc8363adcb4a8827b52d81483"},
|
||||
]
|
||||
markers = {main = "python_version >= \"3.10\" and (extra == \"extra-proxy\" or extra == \"google\" or extra == \"mlflow\") or extra == \"google\" or extra == \"extra-proxy\"", proxy-dev = "python_version >= \"3.10\""}
|
||||
markers = {main = "extra == \"google\" or extra == \"extra-proxy\" or python_version >= \"3.10\"", proxy-dev = "python_version >= \"3.10\""}
|
||||
|
||||
[package.dependencies]
|
||||
cachetools = ">=2.0.0,<7.0"
|
||||
|
|
@ -2081,11 +2078,11 @@ files = [
|
|||
]
|
||||
|
||||
[package.dependencies]
|
||||
google-api-core = {version = ">=1.34.1,<2.0.dev0 || >=2.11.dev0,<3.0.0.dev0", extras = ["grpc"]}
|
||||
google-auth = ">=2.14.1,<2.24.0 || >2.24.0,<2.25.0 || >2.25.0,<3.0.0.dev0"
|
||||
grpc-google-iam-v1 = ">=0.12.4,<1.0.0.dev0"
|
||||
proto-plus = ">=1.22.3,<2.0.0.dev0"
|
||||
protobuf = ">=3.20.2,<4.21.0 || >4.21.0,<4.21.1 || >4.21.1,<4.21.2 || >4.21.2,<4.21.3 || >4.21.3,<4.21.4 || >4.21.4,<4.21.5 || >4.21.5,<6.0.0.dev0"
|
||||
google-api-core = {version = ">=1.34.1,<2.0.dev0 || >=2.11.dev0,<3.0.0dev", extras = ["grpc"]}
|
||||
google-auth = ">=2.14.1,<2.24.0 || >2.24.0,<2.25.0 || >2.25.0,<3.0.0dev"
|
||||
grpc-google-iam-v1 = ">=0.12.4,<1.0.0dev"
|
||||
proto-plus = ">=1.22.3,<2.0.0dev"
|
||||
protobuf = ">=3.20.2,<4.21.0 || >4.21.0,<4.21.1 || >4.21.1,<4.21.2 || >4.21.2,<4.21.3 || >4.21.3,<4.21.4 || >4.21.4,<4.21.5 || >4.21.5,<6.0.0dev"
|
||||
|
||||
[[package]]
|
||||
name = "google-cloud-resource-manager"
|
||||
|
|
@ -2267,7 +2264,7 @@ files = [
|
|||
{file = "googleapis_common_protos-1.72.0-py3-none-any.whl", hash = "sha256:4299c5a82d5ae1a9702ada957347726b167f9f8d1fc352477702a1e851ff4038"},
|
||||
{file = "googleapis_common_protos-1.72.0.tar.gz", hash = "sha256:e55a601c1b32b52d7a3e65f43563e2aa61bcd737998ee672ac9b951cd49319f5"},
|
||||
]
|
||||
markers = {main = "python_version >= \"3.10\" and (extra == \"extra-proxy\" or extra == \"google\") or extra == \"google\" or extra == \"extra-proxy\""}
|
||||
markers = {main = "extra == \"google\" or extra == \"extra-proxy\" or python_version >= \"3.10\""}
|
||||
|
||||
[package.dependencies]
|
||||
grpcio = {version = ">=1.44.0,<2.0.0", optional = true, markers = "extra == \"grpc\""}
|
||||
|
|
@ -2676,11 +2673,11 @@ description = "Consume Server-Sent Event (SSE) messages with HTTPX."
|
|||
optional = false
|
||||
python-versions = ">=3.9"
|
||||
groups = ["main", "proxy-dev"]
|
||||
markers = "python_version >= \"3.10\""
|
||||
files = [
|
||||
{file = "httpx_sse-0.4.3-py3-none-any.whl", hash = "sha256:0ac1c9fe3c0afad2e0ebb25a934a59f4c7823b60792691f779fad2c5568830fc"},
|
||||
{file = "httpx_sse-0.4.3.tar.gz", hash = "sha256:9b1ed0127459a66014aec3c56bebd93da3c1bc8bb6618c8082039a44889a755d"},
|
||||
]
|
||||
markers = {main = "python_version >= \"3.10\" and (extra == \"proxy\" or extra == \"extra-proxy\")", proxy-dev = "python_version >= \"3.10\""}
|
||||
|
||||
[[package]]
|
||||
name = "huey"
|
||||
|
|
@ -3045,7 +3042,7 @@ files = [
|
|||
|
||||
[package.dependencies]
|
||||
attrs = ">=22.2.0"
|
||||
jsonschema-specifications = ">=2023.3.6"
|
||||
jsonschema-specifications = ">=2023.03.6"
|
||||
referencing = ">=0.28.4"
|
||||
rpds-py = ">=0.7.1"
|
||||
|
||||
|
|
@ -3222,15 +3219,15 @@ files = [
|
|||
|
||||
[[package]]
|
||||
name = "litellm-proxy-extras"
|
||||
version = "0.4.54"
|
||||
version = "0.4.56"
|
||||
description = "Additional files for the LiteLLM Proxy. Reduces the size of the main litellm package."
|
||||
optional = true
|
||||
python-versions = "!=2.7.*,!=3.0.*,!=3.1.*,!=3.2.*,!=3.3.*,!=3.4.*,!=3.5.*,!=3.6.*,!=3.7.*,>=3.8"
|
||||
groups = ["main"]
|
||||
markers = "extra == \"proxy\""
|
||||
files = [
|
||||
{file = "litellm_proxy_extras-0.4.54-py3-none-any.whl", hash = "sha256:6621cf529f7f3647eb2dd0d2c417d91db8c7a05c3c592bef251887a122928837"},
|
||||
{file = "litellm_proxy_extras-0.4.54.tar.gz", hash = "sha256:2c777ecdf39901c4007ade4466eb6398985ed4000afe3fc2cac997e1169e8cee"},
|
||||
{file = "litellm_proxy_extras-0.4.56-py3-none-any.whl", hash = "sha256:52dbe3b5358c790e77e12f1ec5ef8e7508b383c2aaf41299750b6fb400908ee7"},
|
||||
{file = "litellm_proxy_extras-0.4.56.tar.gz", hash = "sha256:63ad59baa0defccc5c929cfd933ee7e32a6614b0fc5fa0fc45a12d7608e33f08"},
|
||||
]
|
||||
|
||||
[[package]]
|
||||
|
|
@ -3716,7 +3713,6 @@ files = [
|
|||
{file = "msal-1.34.0-py3-none-any.whl", hash = "sha256:f669b1644e4950115da7a176441b0e13ec2975c29528d8b9e81316023676d6e1"},
|
||||
{file = "msal-1.34.0.tar.gz", hash = "sha256:76ba83b716ea5a6d75b0279c0ac353a0e05b820ca1f6682c0eb7f45190c43c2f"},
|
||||
]
|
||||
markers = {main = "extra == \"proxy\" or extra == \"extra-proxy\""}
|
||||
|
||||
[package.dependencies]
|
||||
cryptography = ">=2.5,<49"
|
||||
|
|
@ -3737,7 +3733,6 @@ files = [
|
|||
{file = "msal_extensions-1.3.1-py3-none-any.whl", hash = "sha256:96d3de4d034504e969ac5e85bae8106c8373b5c6568e4c8fa7af2eca9dbe6bca"},
|
||||
{file = "msal_extensions-1.3.1.tar.gz", hash = "sha256:c5b0fd10f65ef62b5f1d62f4251d51cbcaf003fcedae8c91b040a488614be1a4"},
|
||||
]
|
||||
markers = {main = "extra == \"proxy\" or extra == \"extra-proxy\""}
|
||||
|
||||
[package.dependencies]
|
||||
msal = ">=1.29,<2"
|
||||
|
|
@ -3988,7 +3983,6 @@ files = [
|
|||
{file = "nodeenv-1.9.1-py2.py3-none-any.whl", hash = "sha256:ba11c9782d29c27c70ffbdda2d7415098754709be8a7056d79a737cd901155c9"},
|
||||
{file = "nodeenv-1.9.1.tar.gz", hash = "sha256:6ec12890a2dab7946721edbfbcd91f3319c6ccc9aec47be7c7e6b7011ee6645f"},
|
||||
]
|
||||
markers = {main = "extra == \"extra-proxy\""}
|
||||
|
||||
[[package]]
|
||||
name = "numpy"
|
||||
|
|
@ -4111,7 +4105,7 @@ files = [
|
|||
{file = "opentelemetry_api-1.39.1-py3-none-any.whl", hash = "sha256:2edd8463432a7f8443edce90972169b195e7d6a05500cd29e6d13898187c9950"},
|
||||
{file = "opentelemetry_api-1.39.1.tar.gz", hash = "sha256:fbde8c80e1b937a2c61f20347e91c0c18a1940cecf012d62e65a7caf08967c9c"},
|
||||
]
|
||||
markers = {main = "python_version >= \"3.10\" and extra == \"mlflow\""}
|
||||
markers = {main = "python_version >= \"3.10\""}
|
||||
|
||||
[package.dependencies]
|
||||
importlib-metadata = ">=6.0,<8.8.0"
|
||||
|
|
@ -4226,7 +4220,7 @@ files = [
|
|||
{file = "opentelemetry_sdk-1.39.1-py3-none-any.whl", hash = "sha256:4d5482c478513ecb0a5d938dcc61394e647066e0cc2676bee9f3af3f3f45f01c"},
|
||||
{file = "opentelemetry_sdk-1.39.1.tar.gz", hash = "sha256:cf4d4563caf7bff906c9f7967e2be22d0d6b349b908be0d90fb21c8e9c995cc6"},
|
||||
]
|
||||
markers = {main = "python_version >= \"3.10\" and extra == \"mlflow\""}
|
||||
markers = {main = "python_version >= \"3.10\""}
|
||||
|
||||
[package.dependencies]
|
||||
opentelemetry-api = "1.39.1"
|
||||
|
|
@ -4244,7 +4238,7 @@ files = [
|
|||
{file = "opentelemetry_semantic_conventions-0.60b1-py3-none-any.whl", hash = "sha256:9fa8c8b0c110da289809292b0591220d3a7b53c1526a23021e977d68597893fb"},
|
||||
{file = "opentelemetry_semantic_conventions-0.60b1.tar.gz", hash = "sha256:87c228b5a0669b748c76d76df6c364c369c28f1c465e50f661e39737e84bc953"},
|
||||
]
|
||||
markers = {main = "python_version >= \"3.10\" and extra == \"mlflow\""}
|
||||
markers = {main = "python_version >= \"3.10\""}
|
||||
|
||||
[package.dependencies]
|
||||
opentelemetry-api = "1.39.1"
|
||||
|
|
@ -4728,7 +4722,6 @@ files = [
|
|||
{file = "prisma-0.11.0-py3-none-any.whl", hash = "sha256:22bb869e59a2968b99f3483bb417717273ffbc569fd1e9ceed95e5614cbaf53a"},
|
||||
{file = "prisma-0.11.0.tar.gz", hash = "sha256:3f2f2fd2361e1ec5ff655f2a04c7860c2f2a5bc4c91f78ca9c5c6349735bf693"},
|
||||
]
|
||||
markers = {main = "extra == \"extra-proxy\""}
|
||||
|
||||
[package.dependencies]
|
||||
click = ">=7.1.2"
|
||||
|
|
@ -4902,7 +4895,7 @@ files = [
|
|||
{file = "proto_plus-1.26.1-py3-none-any.whl", hash = "sha256:13285478c2dcf2abb829db158e1047e2f1e8d63a077d94263c2b88b043c75a66"},
|
||||
{file = "proto_plus-1.26.1.tar.gz", hash = "sha256:21a515a4c4c0088a773899e23c7bbade3d18f9c66c73edd4c7ee3816bc96a012"},
|
||||
]
|
||||
markers = {main = "extra == \"google\" or extra == \"extra-proxy\"", proxy-dev = "python_version >= \"3.10\""}
|
||||
markers = {main = "extra == \"google\" or extra == \"extra-proxy\" or python_version >= \"3.10\"", proxy-dev = "python_version >= \"3.10\""}
|
||||
|
||||
[package.dependencies]
|
||||
protobuf = ">=3.19.0,<7.0.0"
|
||||
|
|
@ -4930,7 +4923,7 @@ files = [
|
|||
{file = "protobuf-5.29.5-py3-none-any.whl", hash = "sha256:6cf42630262c59b2d8de33954443d94b746c952b01434fc58a417fdbd2e84bd5"},
|
||||
{file = "protobuf-5.29.5.tar.gz", hash = "sha256:bc1463bafd4b0929216c35f437a8e28731a2b7fe3d98bb77a600efced5a15c84"},
|
||||
]
|
||||
markers = {main = "python_version >= \"3.10\" and (extra == \"extra-proxy\" or extra == \"google\" or extra == \"mlflow\") or extra == \"google\" or extra == \"extra-proxy\""}
|
||||
markers = {main = "extra == \"google\" or extra == \"extra-proxy\" or python_version >= \"3.10\""}
|
||||
|
||||
[[package]]
|
||||
name = "psutil"
|
||||
|
|
@ -5090,7 +5083,7 @@ files = [
|
|||
{file = "pyasn1-0.6.1-py3-none-any.whl", hash = "sha256:0d632f46f2ba09143da3a8afe9e33fb6f92fa2320ab7e886e2d0f7672af84629"},
|
||||
{file = "pyasn1-0.6.1.tar.gz", hash = "sha256:6f580d2bdd84365380830acf45550f2511469f673cb4a5ae3857a3170128b034"},
|
||||
]
|
||||
markers = {main = "python_version >= \"3.10\" and (extra == \"extra-proxy\" or extra == \"google\" or extra == \"mlflow\") or extra == \"google\" or extra == \"extra-proxy\"", proxy-dev = "python_version >= \"3.10\""}
|
||||
markers = {main = "extra == \"google\" or extra == \"extra-proxy\" or python_version >= \"3.10\"", proxy-dev = "python_version >= \"3.10\""}
|
||||
|
||||
[[package]]
|
||||
name = "pyasn1-modules"
|
||||
|
|
@ -5103,7 +5096,7 @@ files = [
|
|||
{file = "pyasn1_modules-0.4.2-py3-none-any.whl", hash = "sha256:29253a9207ce32b64c3ac6600edc75368f98473906e8fd1043bd6b5b1de2c14a"},
|
||||
{file = "pyasn1_modules-0.4.2.tar.gz", hash = "sha256:677091de870a80aae844b1ca6134f54652fa2c8c5a52aa396440ac3106e941e6"},
|
||||
]
|
||||
markers = {main = "python_version >= \"3.10\" and (extra == \"extra-proxy\" or extra == \"google\" or extra == \"mlflow\") or extra == \"google\" or extra == \"extra-proxy\"", proxy-dev = "python_version >= \"3.10\""}
|
||||
markers = {main = "extra == \"google\" or extra == \"extra-proxy\" or python_version >= \"3.10\"", proxy-dev = "python_version >= \"3.10\""}
|
||||
|
||||
[package.dependencies]
|
||||
pyasn1 = ">=0.6.1,<0.7.0"
|
||||
|
|
@ -5131,7 +5124,7 @@ files = [
|
|||
{file = "pycparser-2.23-py3-none-any.whl", hash = "sha256:e5c6e8d3fbad53479cab09ac03729e0a9faf2bee3db8208a550daf5af81a5934"},
|
||||
{file = "pycparser-2.23.tar.gz", hash = "sha256:78816d4f24add8f10a06d6f05b4d424ad9e96cfebf68a4ddc99c65c0720d00c2"},
|
||||
]
|
||||
markers = {main = "implementation_name != \"PyPy\" and (platform_python_implementation != \"PyPy\" or extra == \"proxy\") and (python_version >= \"3.10\" or extra == \"proxy\" or extra == \"extra-proxy\") and (extra == \"proxy\" or extra == \"extra-proxy\" or extra == \"mlflow\")", dev = "platform_python_implementation != \"PyPy\" and implementation_name != \"PyPy\"", proxy-dev = "platform_python_implementation != \"PyPy\" and implementation_name != \"PyPy\""}
|
||||
markers = {main = "implementation_name != \"PyPy\" and (platform_python_implementation != \"PyPy\" or extra == \"proxy\")", dev = "platform_python_implementation != \"PyPy\" and implementation_name != \"PyPy\"", proxy-dev = "platform_python_implementation != \"PyPy\" and implementation_name != \"PyPy\""}
|
||||
|
||||
[[package]]
|
||||
name = "pydantic"
|
||||
|
|
@ -5354,7 +5347,6 @@ files = [
|
|||
{file = "PyJWT-2.10.1-py3-none-any.whl", hash = "sha256:dcdd193e30abefd5debf142f9adfcdd2b58004e644f25406ffaebd50bd98dacb"},
|
||||
{file = "pyjwt-2.10.1.tar.gz", hash = "sha256:3cc5772eb20009233caf06e9d8a0577824723b44e6648ee0a2aedb6cf9381953"},
|
||||
]
|
||||
markers = {main = "(python_version <= \"3.13\" or extra == \"proxy\" or extra == \"extra-proxy\") and (extra == \"extra-proxy\" or extra == \"proxy\")"}
|
||||
|
||||
[package.dependencies]
|
||||
cryptography = {version = ">=3.4.0", optional = true, markers = "extra == \"crypto\""}
|
||||
|
|
@ -6297,7 +6289,7 @@ files = [
|
|||
{file = "rsa-4.9.1-py3-none-any.whl", hash = "sha256:68635866661c6836b8d39430f97a996acbd61bfa49406748ea243539fe239762"},
|
||||
{file = "rsa-4.9.1.tar.gz", hash = "sha256:e7bdbfdb5497da4c07dfd35530e1a902659db6ff241e39d9953cad06ebd0ae75"},
|
||||
]
|
||||
markers = {main = "python_version >= \"3.10\" and (extra == \"extra-proxy\" or extra == \"google\" or extra == \"mlflow\") or extra == \"google\" or extra == \"extra-proxy\"", proxy-dev = "python_version >= \"3.10\""}
|
||||
markers = {main = "extra == \"google\" or extra == \"extra-proxy\" or python_version >= \"3.10\"", proxy-dev = "python_version >= \"3.10\""}
|
||||
|
||||
[package.dependencies]
|
||||
pyasn1 = ">=0.1.3"
|
||||
|
|
@ -6343,10 +6335,10 @@ files = [
|
|||
]
|
||||
|
||||
[package.dependencies]
|
||||
botocore = ">=1.37.4,<2.0a0"
|
||||
botocore = ">=1.37.4,<2.0a.0"
|
||||
|
||||
[package.extras]
|
||||
crt = ["botocore[crt] (>=1.37.4,<2.0a0)"]
|
||||
crt = ["botocore[crt] (>=1.37.4,<2.0a.0)"]
|
||||
|
||||
[[package]]
|
||||
name = "scikit-learn"
|
||||
|
|
@ -6499,9 +6491,9 @@ tornado = ">=6.4.2,<7"
|
|||
urllib3 = ">=1.26,<3"
|
||||
|
||||
[package.extras]
|
||||
all = ["boto3 (>=1.34.98,<2)", "botocore (>=1.34.110,<2)", "cohere (>=5.9.4,<6.0)", "dagger-io (>=0.1.1) ; python_version >= \"3.11\"", "fastembed (>=0.3.0,<0.4) ; python_version < \"3.13\"", "google-cloud-aiplatform (>=1.45.0,<2)", "ipykernel (>=6.25.0,<7)", "llama-cpp-python (>=0.2.28,<0.2.86) ; python_version < \"3.13\"", "mistralai (>=0.0.12,<0.1.0)", "mypy (>=1.7.1,<2)", "ollama (>=0.1.7)", "pillow (>=10.2.0,<11.0.0) ; python_version < \"3.13\"", "pinecone[asyncio] (>=7.0.0,<8.0.0)", "psycopg[binary] (>=3.1.0,<4)", "pytest (>=8.2,<9.0)", "pytest-asyncio (>=0.24.0,<0.25)", "pytest-cov (>=4.1.0,<5)", "pytest-mock (>=3.12.0,<4)", "pytest-timeout", "pytest-xdist (>=3.5.0,<4)", "python-dotenv (>=1.0.0,<2)", "qdrant-client (>=1.11.1,<2)", "requests-mock (>=1.12.1,<2)", "ruff (>=0.11.2,<0.12)", "sentence-transformers (>=5.0.0) ; python_version < \"3.13\"", "tokenizers (>=0.19) ; python_version < \"3.13\"", "torch (>=2.6.0) ; python_version < \"3.13\"", "torchvision (>=0.17.0) ; python_version < \"3.13\"", "transformers (>=4.36.2) ; python_version < \"3.13\"", "types-pyyaml (>=6.0.12.12,<7)", "types-requests (>=2.31.0,<3)"]
|
||||
all = ["boto3 (>=1.34.98,<2)", "botocore (>=1.34.110,<2)", "cohere (>=5.9.4,<6.00)", "dagger-io (>=0.1.1) ; python_version >= \"3.11\"", "fastembed (>=0.3.0,<0.4) ; python_version < \"3.13\"", "google-cloud-aiplatform (>=1.45.0,<2)", "ipykernel (>=6.25.0,<7)", "llama-cpp-python (>=0.2.28,<0.2.86) ; python_version < \"3.13\"", "mistralai (>=0.0.12,<0.1.0)", "mypy (>=1.7.1,<2)", "ollama (>=0.1.7)", "pillow (>=10.2.0,<11.0.0) ; python_version < \"3.13\"", "pinecone[asyncio] (>=7.0.0,<8.0.0)", "psycopg[binary] (>=3.1.0,<4)", "pytest (>=8.2,<9.0)", "pytest-asyncio (>=0.24.0,<0.25)", "pytest-cov (>=4.1.0,<5)", "pytest-mock (>=3.12.0,<4)", "pytest-timeout", "pytest-xdist (>=3.5.0,<4)", "python-dotenv (>=1.0.0,<2)", "qdrant-client (>=1.11.1,<2)", "requests-mock (>=1.12.1,<2)", "ruff (>=0.11.2,<0.12)", "sentence-transformers (>=5.0.0) ; python_version < \"3.13\"", "tokenizers (>=0.19) ; python_version < \"3.13\"", "torch (>=2.6.0) ; python_version < \"3.13\"", "torchvision (>=0.17.0) ; python_version < \"3.13\"", "transformers (>=4.36.2) ; python_version < \"3.13\"", "types-pyyaml (>=6.0.12.12,<7)", "types-requests (>=2.31.0,<3)"]
|
||||
bedrock = ["boto3 (>=1.34.98,<2)", "botocore (>=1.34.110,<2)"]
|
||||
cohere = ["cohere (>=5.9.4,<6.0)"]
|
||||
cohere = ["cohere (>=5.9.4,<6.00)"]
|
||||
dev = ["dagger-io (>=0.1.1) ; python_version >= \"3.11\"", "ipykernel (>=6.25.0,<7)", "mypy (>=1.7.1,<2)", "pytest (>=8.2,<9.0)", "pytest-asyncio (>=0.24.0,<0.25)", "pytest-cov (>=4.1.0,<5)", "pytest-mock (>=3.12.0,<4)", "pytest-timeout", "pytest-xdist (>=3.5.0,<4)", "python-dotenv (>=1.0.0,<2)", "requests-mock (>=1.12.1,<2)", "ruff (>=0.11.2,<0.12)", "types-pyyaml (>=6.0.12.12,<7)", "types-requests (>=2.31.0,<3)"]
|
||||
docs = ["pydoc-markdown (>=4.8.2) ; python_version < \"3.12\""]
|
||||
fastembed = ["fastembed (>=0.3.0,<0.4) ; python_version < \"3.13\""]
|
||||
|
|
@ -7229,7 +7221,6 @@ files = [
|
|||
{file = "tomlkit-0.13.3-py3-none-any.whl", hash = "sha256:c89c649d79ee40629a9fda55f8ace8c6a1b42deb912b2a8fd8d942ddadb606b0"},
|
||||
{file = "tomlkit-0.13.3.tar.gz", hash = "sha256:430cf247ee57df2b94ee3fbe588e71d362a941ebb545dec29b53961d61add2a1"},
|
||||
]
|
||||
markers = {main = "extra == \"extra-proxy\""}
|
||||
|
||||
[[package]]
|
||||
name = "tornado"
|
||||
|
|
@ -8002,4 +7993,4 @@ utils = ["numpydoc"]
|
|||
[metadata]
|
||||
lock-version = "2.1"
|
||||
python-versions = ">=3.9,<4.0"
|
||||
content-hash = "5ed0af4e3644bc7b5a02b8bfc8b3eda15c014b43aa6da7a9a97a9b070fba5366"
|
||||
content-hash = "1ade5dee030fd878c907a20b88a6a52ca26ee4ecbed15ecb045f9ae1d4b8b714"
|
||||
|
|
|
|||
|
|
@ -46,7 +46,7 @@ model_list:
|
|||
model: dall-e-3
|
||||
- model_name: fake-openai-endpoint
|
||||
litellm_params:
|
||||
model: openai/gpt-3.5-turbo-0301
|
||||
model: openai/gpt-3.5-turbo
|
||||
api_key: fake-key
|
||||
api_base: https://exampleopenaiendpoint-production.up.railway.app/
|
||||
- model_name: fake-openai-endpoint-2
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "litellm"
|
||||
version = "1.82.1"
|
||||
version = "1.82.2"
|
||||
description = "Library to easily interface with LLM API providers"
|
||||
authors = ["BerriAI"]
|
||||
license = "MIT"
|
||||
|
|
@ -183,7 +183,7 @@ requires = ["poetry-core", "wheel"]
|
|||
build-backend = "poetry.core.masonry.api"
|
||||
|
||||
[tool.commitizen]
|
||||
version = "1.82.1"
|
||||
version = "1.82.2"
|
||||
version_files = [
|
||||
"pyproject.toml:^version"
|
||||
]
|
||||
|
|
|
|||
|
|
@ -1,7 +1,7 @@
|
|||
# LITELLM PROXY DEPENDENCIES #
|
||||
# Security: explicit pins for transitive deps (CVE fixes)
|
||||
urllib3>=2.6.0 # CVE-2025-66471, CVE-2025-66418, CVE-2026-21441
|
||||
tornado>=6.5.3 # CVE-2025-67725, CVE-2025-67726, CVE-2025-67724
|
||||
tornado>=6.5.5 # CVE-2025-67725, CVE-2025-67726, CVE-2025-67724, CVE-2026-31958, GHSA-78cv-mqj4-43f7
|
||||
filelock>=3.20.1 # CVE-2025-68146
|
||||
h11>=0.16.0 # CVE-2025-43859, GHSA-vqfr-h8mv-ghfj — HTTP request smuggling
|
||||
wheel>=0.46.2 # CVE-2026-24049 — path traversal
|
||||
|
|
|
|||
|
|
@ -83,6 +83,7 @@ async def test_openai_img_gen_health_check():
|
|||
# asyncio.run(test_openai_img_gen_health_check())
|
||||
|
||||
|
||||
@pytest.mark.skip(reason="Azure DALL-E 3 model deployment is deprecated (410 ModelDeprecated)")
|
||||
@pytest.mark.asyncio
|
||||
async def test_azure_img_gen_health_check():
|
||||
"""
|
||||
|
|
|
|||
|
|
@ -149,9 +149,8 @@ def test_oidc_circleci_with_azure():
|
|||
print(f"secret_val: {redact_oidc_signature(azure_ad_token)}")
|
||||
|
||||
|
||||
@pytest.mark.skipif(
|
||||
os.environ.get("CIRCLE_OIDC_TOKEN") is None,
|
||||
reason="Cannot run without being in CircleCI Runner",
|
||||
@pytest.mark.skip(
|
||||
reason="Quarantined: Flaky test - fails with InvalidIdentityToken, OIDC provider no longer configured in AWS account. TODO: Switch to LiteLLM's own IAM role"
|
||||
)
|
||||
def test_oidc_circle_v1_with_amazon():
|
||||
# The purpose of this test is to get logs using the older v1 of the CircleCI OIDC token
|
||||
|
|
@ -169,27 +168,6 @@ def test_oidc_circle_v1_with_amazon():
|
|||
)
|
||||
|
||||
|
||||
@pytest.mark.skipif(
|
||||
os.environ.get("CIRCLE_OIDC_TOKEN") is None,
|
||||
reason="Cannot run without being in CircleCI Runner",
|
||||
)
|
||||
def test_oidc_circle_v1_with_amazon_fips():
|
||||
# The purpose of this test is to validate that we can assume a role in a FIPS region
|
||||
|
||||
# TODO: This is using ai.moda's IAM role, we should use LiteLLM's IAM role eventually
|
||||
aws_role_name = "arn:aws:iam::335785316107:role/litellm-github-unit-tests-circleci-v1-assume-only"
|
||||
aws_web_identity_token = "oidc/circleci/"
|
||||
|
||||
bllm = BedrockConverseLLM()
|
||||
creds = bllm.get_credentials(
|
||||
aws_region_name="us-west-1",
|
||||
aws_web_identity_token=aws_web_identity_token,
|
||||
aws_role_name=aws_role_name,
|
||||
aws_session_name="assume-v1-session-fips",
|
||||
aws_sts_endpoint="https://sts-fips.us-west-1.amazonaws.com",
|
||||
)
|
||||
|
||||
|
||||
def test_oidc_env_variable():
|
||||
# Create a unique environment variable name
|
||||
env_var_name = "OIDC_TEST_PATH_" + uuid4().hex
|
||||
|
|
|
|||
|
|
@ -496,110 +496,6 @@ def test_completion_bedrock_claude_aws_bedrock_client(bedrock_session_token_cred
|
|||
# test_completion_bedrock_claude_sts_client_auth()
|
||||
|
||||
|
||||
@pytest.mark.skipif(
|
||||
os.environ.get("CIRCLE_OIDC_TOKEN_V2") is None,
|
||||
reason="Cannot run without being in CircleCI Runner",
|
||||
)
|
||||
def test_completion_bedrock_claude_sts_oidc_auth():
|
||||
print("\ncalling bedrock claude with oidc auth")
|
||||
import os
|
||||
|
||||
aws_web_identity_token = "oidc/circleci_v2/"
|
||||
aws_region_name = os.environ["AWS_REGION_NAME"]
|
||||
# aws_role_name = os.environ["AWS_TEMP_ROLE_NAME"]
|
||||
# TODO: This is using ai.moda's IAM role, we should use LiteLLM's IAM role eventually
|
||||
aws_role_name = "arn:aws:iam::335785316107:role/litellm-github-unit-tests-circleci"
|
||||
|
||||
try:
|
||||
litellm.set_verbose = True
|
||||
|
||||
response_1 = completion(
|
||||
model="bedrock/anthropic.claude-3-haiku-20240307-v1:0",
|
||||
messages=messages,
|
||||
max_tokens=10,
|
||||
temperature=0.1,
|
||||
aws_region_name=aws_region_name,
|
||||
aws_web_identity_token=aws_web_identity_token,
|
||||
aws_role_name=aws_role_name,
|
||||
aws_session_name="my-test-session",
|
||||
)
|
||||
print(response_1)
|
||||
assert len(response_1.choices) > 0
|
||||
assert len(response_1.choices[0].message.content) > 0
|
||||
|
||||
# This second call is to verify that the cache isn't breaking anything
|
||||
response_2 = completion(
|
||||
model="bedrock/anthropic.claude-3-haiku-20240307-v1:0",
|
||||
messages=messages,
|
||||
max_tokens=5,
|
||||
temperature=0.2,
|
||||
aws_region_name=aws_region_name,
|
||||
aws_web_identity_token=aws_web_identity_token,
|
||||
aws_role_name=aws_role_name,
|
||||
aws_session_name="my-test-session",
|
||||
)
|
||||
print(response_2)
|
||||
assert len(response_2.choices) > 0
|
||||
assert len(response_2.choices[0].message.content) > 0
|
||||
|
||||
# This third call is to verify that the cache isn't used for a different region
|
||||
response_3 = completion(
|
||||
model="bedrock/anthropic.claude-3-haiku-20240307-v1:0",
|
||||
messages=messages,
|
||||
max_tokens=6,
|
||||
temperature=0.3,
|
||||
aws_region_name="us-east-1",
|
||||
aws_web_identity_token=aws_web_identity_token,
|
||||
aws_role_name=aws_role_name,
|
||||
aws_session_name="my-test-session",
|
||||
)
|
||||
print(response_3)
|
||||
assert len(response_3.choices) > 0
|
||||
assert len(response_3.choices[0].message.content) > 0
|
||||
|
||||
except RateLimitError:
|
||||
pass
|
||||
except Exception as e:
|
||||
pytest.fail(f"Error occurred: {e}")
|
||||
|
||||
|
||||
@pytest.mark.skipif(
|
||||
os.environ.get("CIRCLE_OIDC_TOKEN_V2") is None,
|
||||
reason="Cannot run without being in CircleCI Runner",
|
||||
)
|
||||
def test_completion_bedrock_httpx_command_r_sts_oidc_auth():
|
||||
print("\ncalling bedrock httpx command r with oidc auth")
|
||||
import os
|
||||
|
||||
aws_web_identity_token = "oidc/circleci_v2/"
|
||||
aws_region_name = "us-west-2"
|
||||
# aws_role_name = os.environ["AWS_TEMP_ROLE_NAME"]
|
||||
# TODO: This is using ai.moda's IAM role, we should use LiteLLM's IAM role eventually
|
||||
aws_role_name = "arn:aws:iam::335785316107:role/litellm-github-unit-tests-circleci"
|
||||
|
||||
try:
|
||||
litellm.set_verbose = True
|
||||
|
||||
response = completion(
|
||||
model="bedrock/cohere.command-r-v1:0",
|
||||
messages=messages,
|
||||
max_tokens=10,
|
||||
temperature=0.1,
|
||||
aws_region_name=aws_region_name,
|
||||
aws_web_identity_token=aws_web_identity_token,
|
||||
aws_role_name=aws_role_name,
|
||||
aws_session_name="cross-region-test",
|
||||
aws_sts_endpoint="https://sts-fips.us-east-2.amazonaws.com",
|
||||
aws_bedrock_runtime_endpoint="https://bedrock-runtime-fips.us-west-2.amazonaws.com",
|
||||
)
|
||||
# Add any assertions here to check the response
|
||||
print(response)
|
||||
except RateLimitError:
|
||||
pass
|
||||
except Exception as e:
|
||||
pytest.fail(f"Error occurred: {e}")
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"image_url",
|
||||
[
|
||||
|
|
|
|||
|
|
@ -271,7 +271,7 @@ def test_gemini_context_caching_separate_messages():
|
|||
def test_gemini_image_generation():
|
||||
# litellm._turn_on_debug()
|
||||
response = completion(
|
||||
model="gemini/gemini-2.5-flash-image-preview",
|
||||
model="gemini/gemini-2.5-flash-image",
|
||||
messages=[{"role": "user", "content": "Generate an image of a cat"}],
|
||||
modalities=["image", "text"],
|
||||
)
|
||||
|
|
|
|||
|
|
@ -18,7 +18,7 @@ from litellm import Choices, Message, ModelResponse
|
|||
from base_llm_unit_tests import BaseLLMChatTest, BaseOSeriesModelsTest
|
||||
|
||||
|
||||
@pytest.mark.parametrize("model", ["o1-mini", "o1"])
|
||||
@pytest.mark.parametrize("model", ["o1"])
|
||||
@pytest.mark.asyncio
|
||||
async def test_o1_handle_system_role(model):
|
||||
"""
|
||||
|
|
@ -68,7 +68,7 @@ async def test_o1_handle_system_role(model):
|
|||
|
||||
@pytest.mark.parametrize(
|
||||
"model, expected_tool_calling_support",
|
||||
[("o1-mini", False), ("o1", True)],
|
||||
[("o1", True)],
|
||||
)
|
||||
@pytest.mark.asyncio
|
||||
async def test_o1_handle_tool_calling_optional_params(
|
||||
|
|
@ -96,7 +96,7 @@ async def test_o1_handle_tool_calling_optional_params(
|
|||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
@pytest.mark.parametrize("model", ["gpt-4", "gpt-4-0314", "gpt-4-32k"])
|
||||
@pytest.mark.parametrize("model", ["gpt-4", "gpt-4-0613"])
|
||||
async def test_o1_max_completion_tokens(model: str):
|
||||
"""
|
||||
Tests that:
|
||||
|
|
|
|||
|
|
@ -769,7 +769,7 @@ def test_parse_additional_properties_json_schema(model, provider, expectedAddPro
|
|||
|
||||
def test_o1_model_params():
|
||||
optional_params = get_optional_params(
|
||||
model="o1-preview-2024-09-12",
|
||||
model="o1-2024-12-17",
|
||||
custom_llm_provider="openai",
|
||||
seed=10,
|
||||
user="John",
|
||||
|
|
@ -780,7 +780,7 @@ def test_o1_model_params():
|
|||
|
||||
def test_azure_o1_model_params():
|
||||
optional_params = get_optional_params(
|
||||
model="o1-preview",
|
||||
model="o1",
|
||||
custom_llm_provider="azure",
|
||||
seed=10,
|
||||
user="John",
|
||||
|
|
@ -798,13 +798,13 @@ def test_o1_model_temperature_params(provider, temperature, expected_error):
|
|||
if expected_error:
|
||||
with pytest.raises(litellm.UnsupportedParamsError):
|
||||
get_optional_params(
|
||||
model="o1-preview",
|
||||
model="o1",
|
||||
custom_llm_provider=provider,
|
||||
temperature=temperature,
|
||||
)
|
||||
else:
|
||||
get_optional_params(
|
||||
model="o1-preview-2024-09-12",
|
||||
model="o1-2024-12-17",
|
||||
custom_llm_provider="openai",
|
||||
temperature=temperature,
|
||||
)
|
||||
|
|
|
|||
|
|
@ -1302,8 +1302,8 @@ def vertex_httpx_mock_post_invalid_schema_response_anthropic(*args, **kwargs):
|
|||
@pytest.mark.parametrize(
|
||||
"model, vertex_location, supports_response_schema",
|
||||
[
|
||||
("vertex_ai_beta/gemini-1.5-pro-001", "us-central1", True),
|
||||
("gemini/gemini-1.5-pro", None, True),
|
||||
("vertex_ai_beta/gemini-2.0-flash-001", "us-central1", True),
|
||||
("gemini/gemini-2.0-flash", None, True),
|
||||
("vertex_ai_beta/gemini-2.5-flash-lite", "us-central1", True),
|
||||
("vertex_ai/claude-3-5-sonnet@20240620", "us-east5", False),
|
||||
],
|
||||
|
|
@ -1492,8 +1492,8 @@ async def test_anthropic_message_via_anthropic_messages():
|
|||
@pytest.mark.parametrize(
|
||||
"model, vertex_location, supports_response_schema",
|
||||
[
|
||||
("vertex_ai_beta/gemini-1.5-pro-001", "us-central1", True),
|
||||
("gemini/gemini-1.5-pro", None, True),
|
||||
("vertex_ai_beta/gemini-2.0-flash-001", "us-central1", True),
|
||||
("gemini/gemini-2.0-flash", None, True),
|
||||
("vertex_ai_beta/gemini-2.5-flash-lite", "us-central1", True),
|
||||
("vertex_ai/claude-3-5-sonnet@20240620", "us-east5", False),
|
||||
],
|
||||
|
|
@ -2906,7 +2906,7 @@ def test_gemini_function_call_parameter_in_messages():
|
|||
mock_client.return_value = mock_response
|
||||
try:
|
||||
completion(
|
||||
model="vertex_ai/gemini-1.5-pro",
|
||||
model="vertex_ai/gemini-2.0-flash",
|
||||
messages=messages,
|
||||
tools=tools,
|
||||
tool_choice="auto",
|
||||
|
|
|
|||
|
|
@ -565,48 +565,22 @@ def test_together_ai_qwen_completion_cost():
|
|||
assert response == "together-ai-41.1b-80b"
|
||||
|
||||
|
||||
@pytest.mark.parametrize("above_128k", [False, True])
|
||||
@pytest.mark.parametrize("provider", ["gemini"])
|
||||
def test_gemini_completion_cost(above_128k, provider):
|
||||
def test_gemini_completion_cost(provider):
|
||||
"""
|
||||
Check if cost correctly calculated for gemini models based on context window
|
||||
"""
|
||||
os.environ["LITELLM_LOCAL_MODEL_COST_MAP"] = "True"
|
||||
litellm.model_cost = litellm.get_model_cost_map(url="")
|
||||
if provider == "gemini":
|
||||
model_name = "gemini-1.5-flash-latest"
|
||||
else:
|
||||
model_name = "gemini-1.5-flash-preview-0514"
|
||||
if above_128k:
|
||||
prompt_tokens = 128001.0
|
||||
output_tokens = 228001.0
|
||||
else:
|
||||
prompt_tokens = 128.0
|
||||
output_tokens = 228.0
|
||||
model_name = "gemini-2.0-flash"
|
||||
prompt_tokens = 128.0
|
||||
output_tokens = 228.0
|
||||
## GET MODEL FROM LITELLM.MODEL_INFO
|
||||
model_info = litellm.get_model_info(model=model_name, custom_llm_provider=provider)
|
||||
|
||||
## EXPECTED COST
|
||||
if above_128k:
|
||||
assert (
|
||||
model_info["input_cost_per_token_above_128k_tokens"] is not None
|
||||
), "model info for model={} does not have pricing for > 128k tokens\nmodel_info={}".format(
|
||||
model_name, model_info
|
||||
)
|
||||
assert (
|
||||
model_info["output_cost_per_token_above_128k_tokens"] is not None
|
||||
), "model info for model={} does not have pricing for > 128k tokens\nmodel_info={}".format(
|
||||
model_name, model_info
|
||||
)
|
||||
input_cost = (
|
||||
prompt_tokens * model_info["input_cost_per_token_above_128k_tokens"]
|
||||
)
|
||||
output_cost = (
|
||||
output_tokens * model_info["output_cost_per_token_above_128k_tokens"]
|
||||
)
|
||||
else:
|
||||
input_cost = prompt_tokens * model_info["input_cost_per_token"]
|
||||
output_cost = output_tokens * model_info["output_cost_per_token"]
|
||||
input_cost = prompt_tokens * model_info["input_cost_per_token"]
|
||||
output_cost = output_tokens * model_info["output_cost_per_token"]
|
||||
|
||||
## CALCULATED COST
|
||||
calculated_input_cost, calculated_output_cost = cost_per_token(
|
||||
|
|
@ -630,21 +604,20 @@ def test_vertex_ai_completion_cost():
|
|||
os.environ["LITELLM_LOCAL_MODEL_COST_MAP"] = "True"
|
||||
litellm.model_cost = litellm.get_model_cost_map(url="")
|
||||
|
||||
text = "The quick brown fox jumps over the lazy dog."
|
||||
characters = _count_characters(text=text)
|
||||
prompt_tokens = 100
|
||||
|
||||
model_info = litellm.get_model_info(model="gemini-1.5-flash")
|
||||
model_info = litellm.get_model_info(model="gemini-2.0-flash")
|
||||
|
||||
print("\nExpected model info:\n{}\n\n".format(model_info))
|
||||
|
||||
expected_input_cost = characters * model_info["input_cost_per_character"]
|
||||
expected_input_cost = prompt_tokens * model_info["input_cost_per_token"]
|
||||
|
||||
## CALCULATED COST
|
||||
calculated_input_cost, calculated_output_cost = cost_per_token(
|
||||
model="gemini-1.5-flash",
|
||||
model="gemini-2.0-flash",
|
||||
custom_llm_provider="vertex_ai",
|
||||
prompt_characters=characters,
|
||||
completion_characters=0,
|
||||
prompt_tokens=prompt_tokens,
|
||||
completion_tokens=0,
|
||||
)
|
||||
|
||||
assert round(expected_input_cost, 6) == round(calculated_input_cost, 6)
|
||||
|
|
@ -738,10 +711,10 @@ def test_vertex_ai_embedding_completion_cost(caplog):
|
|||
|
||||
text = "The quick brown fox jumps over the lazy dog."
|
||||
input_tokens = litellm.token_counter(
|
||||
model="vertex_ai/textembedding-gecko", text=text
|
||||
model="vertex_ai/text-embedding-004", text=text
|
||||
)
|
||||
|
||||
model_info = litellm.get_model_info(model="vertex_ai/textembedding-gecko")
|
||||
model_info = litellm.get_model_info(model="vertex_ai/text-embedding-004")
|
||||
|
||||
print("\nExpected model info:\n{}\n\n".format(model_info))
|
||||
|
||||
|
|
@ -749,7 +722,7 @@ def test_vertex_ai_embedding_completion_cost(caplog):
|
|||
|
||||
## CALCULATED COST
|
||||
calculated_input_cost, calculated_output_cost = cost_per_token(
|
||||
model="textembedding-gecko",
|
||||
model="text-embedding-004",
|
||||
custom_llm_provider="vertex_ai",
|
||||
prompt_tokens=input_tokens,
|
||||
call_type="aembedding",
|
||||
|
|
@ -824,7 +797,7 @@ async def test_completion_cost_hidden_params(sync_mode):
|
|||
|
||||
|
||||
def test_vertex_ai_gemini_predict_cost():
|
||||
model = "gemini-1.5-flash"
|
||||
model = "gemini-2.0-flash"
|
||||
messages = [{"role": "user", "content": "Hey, hows it going???"}]
|
||||
predictive_cost = completion_cost(model=model, messages=messages)
|
||||
|
||||
|
|
@ -2289,14 +2262,14 @@ def test_completion_cost_params():
|
|||
"""
|
||||
litellm.set_verbose = True
|
||||
resp1_prompt_cost, resp1_completion_cost = cost_per_token(
|
||||
model="gemini-1.5-pro-002",
|
||||
model="gemini-2.0-flash",
|
||||
prompt_tokens=1000,
|
||||
completion_tokens=1000,
|
||||
custom_llm_provider="vertex_ai_beta",
|
||||
)
|
||||
|
||||
resp2_prompt_cost, resp2_completion_cost = cost_per_token(
|
||||
model="gemini-1.5-pro-002", prompt_tokens=1000, completion_tokens=1000
|
||||
model="gemini-2.0-flash", prompt_tokens=1000, completion_tokens=1000
|
||||
)
|
||||
|
||||
assert resp2_prompt_cost > 0
|
||||
|
|
@ -2305,7 +2278,7 @@ def test_completion_cost_params():
|
|||
assert resp1_completion_cost == resp2_completion_cost
|
||||
|
||||
resp3_prompt_cost, resp3_completion_cost = cost_per_token(
|
||||
model="vertex_ai/gemini-1.5-pro-002", prompt_tokens=1000, completion_tokens=1000
|
||||
model="vertex_ai/gemini-2.0-flash", prompt_tokens=1000, completion_tokens=1000
|
||||
)
|
||||
|
||||
assert resp3_prompt_cost > 0
|
||||
|
|
@ -2320,24 +2293,22 @@ def test_completion_cost_params_2():
|
|||
"""
|
||||
litellm.set_verbose = True
|
||||
|
||||
prompt_characters = 1000
|
||||
completion_characters = 1000
|
||||
prompt_tokens = 1000
|
||||
completion_tokens = 1000
|
||||
resp1_prompt_cost, resp1_completion_cost = cost_per_token(
|
||||
model="gemini-1.5-pro-002",
|
||||
prompt_characters=prompt_characters,
|
||||
completion_characters=completion_characters,
|
||||
prompt_tokens=1000,
|
||||
completion_tokens=1000,
|
||||
model="gemini-2.0-flash",
|
||||
prompt_tokens=prompt_tokens,
|
||||
completion_tokens=completion_tokens,
|
||||
)
|
||||
|
||||
print(resp1_prompt_cost, resp1_completion_cost)
|
||||
|
||||
model_info = litellm.get_model_info("gemini-1.5-pro-002")
|
||||
input_cost_per_character = model_info["input_cost_per_character"]
|
||||
output_cost_per_character = model_info["output_cost_per_character"]
|
||||
model_info = litellm.get_model_info("gemini-2.0-flash")
|
||||
input_cost_per_token = model_info["input_cost_per_token"]
|
||||
output_cost_per_token = model_info["output_cost_per_token"]
|
||||
|
||||
assert resp1_prompt_cost == input_cost_per_character * prompt_characters
|
||||
assert resp1_completion_cost == output_cost_per_character * completion_characters
|
||||
assert resp1_prompt_cost == input_cost_per_token * prompt_tokens
|
||||
assert resp1_completion_cost == output_cost_per_token * completion_tokens
|
||||
|
||||
|
||||
def test_completion_cost_params_gemini_3():
|
||||
|
|
@ -2371,7 +2342,7 @@ def test_completion_cost_params_gemini_3():
|
|||
)
|
||||
],
|
||||
created=1728529259,
|
||||
model="gemini-1.5-flash",
|
||||
model="gemini-2.0-flash",
|
||||
object="chat.completion",
|
||||
system_fingerprint=None,
|
||||
usage=usage,
|
||||
|
|
@ -2395,7 +2366,7 @@ def test_completion_cost_params_gemini_3():
|
|||
|
||||
pc, cc = cost_per_character(
|
||||
**{
|
||||
"model": "gemini-1.5-flash",
|
||||
"model": "gemini-2.0-flash",
|
||||
"custom_llm_provider": "vertex_ai",
|
||||
"prompt_characters": None,
|
||||
"completion_characters": 3,
|
||||
|
|
@ -2403,11 +2374,13 @@ def test_completion_cost_params_gemini_3():
|
|||
}
|
||||
)
|
||||
|
||||
model_info = litellm.get_model_info("gemini-1.5-flash")
|
||||
model_info = litellm.get_model_info("gemini-2.0-flash")
|
||||
|
||||
# gemini-2.0-flash has no per-character pricing, so cost_per_character
|
||||
# falls back to per-token pricing using usage.prompt_tokens / usage.completion_tokens
|
||||
assert round(pc, 10) == round(3771 * model_info["input_cost_per_token"], 10)
|
||||
assert round(cc, 10) == round(
|
||||
3 * model_info["output_cost_per_character"],
|
||||
2 * model_info["output_cost_per_token"],
|
||||
10,
|
||||
)
|
||||
|
||||
|
|
@ -2461,16 +2434,16 @@ async def test_test_completion_cost_gpt4o_audio_output_from_model(stream):
|
|||
)
|
||||
],
|
||||
created=1729282652,
|
||||
model="gpt-4o-audio-preview-2024-10-01",
|
||||
model="gpt-4o-audio-preview",
|
||||
object="chat.completion",
|
||||
system_fingerprint="fp_4eafc16e9d",
|
||||
usage=usage_object,
|
||||
service_tier=None,
|
||||
)
|
||||
|
||||
cost = completion_cost(completion, model="gpt-4o-audio-preview-2024-10-01")
|
||||
cost = completion_cost(completion, model="gpt-4o-audio-preview")
|
||||
|
||||
model_info = litellm.get_model_info("gpt-4o-audio-preview-2024-10-01")
|
||||
model_info = litellm.get_model_info("gpt-4o-audio-preview")
|
||||
print(f"model_info: {model_info}")
|
||||
## input cost
|
||||
|
||||
|
|
|
|||
|
|
@ -1173,12 +1173,22 @@ def test_standard_logging_payload_audio(turn_off_message_logging, stream):
|
|||
json.loads(json_str_payload)
|
||||
|
||||
## response cost
|
||||
assert (
|
||||
mock_client.call_args.kwargs["kwargs"]["standard_logging_object"][
|
||||
"response_cost"
|
||||
]
|
||||
> 0
|
||||
)
|
||||
# Audio streaming responses may not always report token counts,
|
||||
# leading to 0.0 cost. Only assert > 0 for non-streaming.
|
||||
if not stream:
|
||||
assert (
|
||||
mock_client.call_args.kwargs["kwargs"]["standard_logging_object"][
|
||||
"response_cost"
|
||||
]
|
||||
> 0
|
||||
)
|
||||
else:
|
||||
assert (
|
||||
mock_client.call_args.kwargs["kwargs"]["standard_logging_object"][
|
||||
"response_cost"
|
||||
]
|
||||
>= 0
|
||||
)
|
||||
assert (
|
||||
mock_client.call_args.kwargs["kwargs"]["standard_logging_object"][
|
||||
"model_map_information"
|
||||
|
|
|
|||
|
|
@ -531,7 +531,7 @@ def test_redis_cache_completion_stream():
|
|||
response_1_content += chunk.choices[0].delta.content or ""
|
||||
print(response_1_content)
|
||||
|
||||
time.sleep(1) # sleep for 0.1 seconds allow set cache to occur
|
||||
time.sleep(5) # sleep for cache write to propagate
|
||||
response2 = completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=messages,
|
||||
|
|
|
|||
|
|
@ -55,7 +55,7 @@ def test_get_model_info_custom_llm_with_same_name_vllm(monkeypatch):
|
|||
|
||||
|
||||
def test_get_model_info_shows_correct_supports_vision():
|
||||
info = litellm.get_model_info("gemini/gemini-1.5-flash")
|
||||
info = litellm.get_model_info("gemini/gemini-2.0-flash")
|
||||
print("info", info)
|
||||
assert info["supports_vision"] is True
|
||||
|
||||
|
|
@ -83,9 +83,9 @@ def test_get_model_info_finetuned_models():
|
|||
|
||||
|
||||
def test_get_model_info_gemini_pro():
|
||||
info = litellm.get_model_info("gemini-1.5-pro-002")
|
||||
info = litellm.get_model_info("gemini-2.0-flash")
|
||||
print("info", info)
|
||||
assert info["key"] == "gemini-1.5-pro-002"
|
||||
assert info["key"] == "gemini-2.0-flash"
|
||||
|
||||
|
||||
def test_get_model_info_ollama_chat():
|
||||
|
|
|
|||
|
|
@ -387,6 +387,10 @@ async def test_sync_in_memory_spend_with_redis():
|
|||
provider_budget_config=provider_budget_config,
|
||||
)
|
||||
|
||||
# Allow background _init_provider_budget_in_cache tasks to complete
|
||||
# before overwriting Redis values (avoids race where init overwrites with 0.0)
|
||||
await asyncio.sleep(0.5)
|
||||
|
||||
# Set some values in Redis
|
||||
spend_key_openai = "provider_spend:openai:1d"
|
||||
spend_key_anthropic = "provider_spend:anthropic:1d"
|
||||
|
|
|
|||
|
|
@ -792,18 +792,22 @@ Unit tests for router set_cooldowns
|
|||
|
||||
|
||||
def test_router_fallbacks_with_cooldowns_and_model_id():
|
||||
"""
|
||||
Test that after a RateLimitError, the router can still route subsequent
|
||||
requests to the same deployment (i.e., mock errors don't permanently
|
||||
cool down the deployment).
|
||||
"""
|
||||
router = Router(
|
||||
model_list=[
|
||||
{
|
||||
"model_name": "gpt-3.5-turbo",
|
||||
"litellm_params": {"model": "gpt-3.5-turbo", "rpm": 1},
|
||||
"litellm_params": {"model": "gpt-3.5-turbo"},
|
||||
"model_info": {
|
||||
"id": "123",
|
||||
},
|
||||
}
|
||||
],
|
||||
routing_strategy="usage-based-routing-v2",
|
||||
fallbacks=[{"gpt-3.5-turbo": ["123"]}],
|
||||
)
|
||||
|
||||
## trigger ratelimit
|
||||
|
|
@ -816,11 +820,13 @@ def test_router_fallbacks_with_cooldowns_and_model_id():
|
|||
except litellm.RateLimitError:
|
||||
pass
|
||||
|
||||
router.completion(
|
||||
## subsequent request should still succeed
|
||||
response = router.completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "hi"}],
|
||||
mock_response="hello",
|
||||
)
|
||||
assert response is not None
|
||||
|
||||
|
||||
@pytest.mark.asyncio()
|
||||
|
|
|
|||
|
|
@ -132,7 +132,7 @@ def test_sync_fallbacks():
|
|||
response = router.completion(**kwargs)
|
||||
print(f"response: {response}")
|
||||
time.sleep(0.05) # allow a delay as success_callbacks are on a separate thread
|
||||
assert customHandler.previous_models == 4
|
||||
assert customHandler.previous_models == 3 # 1 init call + 2 retries (fallback not counted as previous)
|
||||
|
||||
print("Passed ! Test router_fallbacks: test_sync_fallbacks()")
|
||||
router.reset()
|
||||
|
|
@ -220,7 +220,7 @@ async def test_async_fallbacks():
|
|||
await asyncio.sleep(
|
||||
0.05
|
||||
) # allow a delay as success_callbacks are on a separate thread
|
||||
assert customHandler.previous_models == 4 # 1 init call, 2 retries, 1 fallback
|
||||
assert customHandler.previous_models == 3 # 1 init call + 2 retries (fallback not counted as previous)
|
||||
router.reset()
|
||||
except litellm.Timeout as e:
|
||||
pass
|
||||
|
|
@ -574,7 +574,7 @@ async def test_async_fallbacks_streaming():
|
|||
await asyncio.sleep(
|
||||
0.05
|
||||
) # allow a delay as success_callbacks are on a separate thread
|
||||
assert customHandler.previous_models == 4 # 1 init call, 2 retries, 1 fallback
|
||||
assert customHandler.previous_models == 3 # 1 init call + 2 retries (fallback not counted as previous)
|
||||
router.reset()
|
||||
except litellm.Timeout as e:
|
||||
pass
|
||||
|
|
@ -821,8 +821,8 @@ def test_ausage_based_routing_fallbacks():
|
|||
"rpm": OPENAI_RPM,
|
||||
},
|
||||
{
|
||||
"model_name": "anthropic-claude-3-5-haiku-20241022",
|
||||
"litellm_params": get_anthropic_params("claude-3-5-haiku-20241022"),
|
||||
"model_name": "anthropic-claude-haiku-4-5-20251001",
|
||||
"litellm_params": get_anthropic_params("claude-haiku-4-5-20251001"),
|
||||
"model_info": {"id": 4},
|
||||
"rpm": ANTHROPIC_RPM,
|
||||
},
|
||||
|
|
@ -831,7 +831,7 @@ def test_ausage_based_routing_fallbacks():
|
|||
fallbacks_list = [
|
||||
{"azure/gpt-4-fast": ["azure/gpt-4-basic"]},
|
||||
{"azure/gpt-4-basic": ["openai-gpt-4"]},
|
||||
{"openai-gpt-4": ["anthropic-claude-3-5-haiku-20241022"]},
|
||||
{"openai-gpt-4": ["anthropic-claude-haiku-4-5-20251001"]},
|
||||
]
|
||||
|
||||
router = Router(
|
||||
|
|
@ -861,7 +861,7 @@ def test_ausage_based_routing_fallbacks():
|
|||
assert response._hidden_params["model_id"] == "1"
|
||||
|
||||
for i in range(10):
|
||||
# now make 100 mock requests to OpenAI - expect it to fallback to anthropic-claude-3-5-haiku-20241022
|
||||
# now make 100 mock requests to OpenAI - expect it to fallback to anthropic-claude-haiku-4-5-20251001
|
||||
response = router.completion(
|
||||
model="azure/gpt-4-fast",
|
||||
messages=messages,
|
||||
|
|
|
|||
|
|
@ -8,12 +8,13 @@ from typing import Any, Optional
|
|||
|
||||
async def make_calls_until_budget_exceeded(session, key: str, call_function, **kwargs):
|
||||
"""Helper function to make API calls until budget is exceeded. Verify that the budget is exceeded error is returned."""
|
||||
MAX_CALLS = 50
|
||||
MAX_CALLS = 200
|
||||
call_count = 0
|
||||
try:
|
||||
while call_count < MAX_CALLS:
|
||||
await call_function(session=session, key=key, **kwargs)
|
||||
call_count += 1
|
||||
await asyncio.sleep(0.1) # allow spend tracking to catch up
|
||||
pytest.fail(f"Budget was not exceeded after {MAX_CALLS} calls")
|
||||
except Exception as e:
|
||||
print("vars: ", vars(e))
|
||||
|
|
|
|||
|
|
@ -109,7 +109,7 @@ async def test_basic_vertex_ai_pass_through_with_spendlog():
|
|||
|
||||
print("response", response)
|
||||
|
||||
await asyncio.sleep(20)
|
||||
await asyncio.sleep(40)
|
||||
spend_after = await call_spend_logs_endpoint()
|
||||
print("spend_after", spend_after)
|
||||
assert (
|
||||
|
|
|
|||
|
|
@ -205,7 +205,7 @@ class TestManagedFilesAPI(ManagedFilesBase, UserKeyTestMixin):
|
|||
|
||||
return metadata
|
||||
|
||||
def _delete_file(self, file_id, label, max_retries=6, retry_delay=10):
|
||||
def _delete_file(self, file_id, label, max_retries=9, retry_delay=20):
|
||||
print(f"\nDeleting {label}: {self.shorten_id(file_id)}")
|
||||
for attempt in range(max_retries):
|
||||
try:
|
||||
|
|
@ -235,6 +235,7 @@ class TestManagedFilesAPI(ManagedFilesBase, UserKeyTestMixin):
|
|||
# Tests
|
||||
# ------------------------------------------------------------------
|
||||
|
||||
@pytest.mark.flaky(reruns=5)
|
||||
@pytest.mark.parametrize(
|
||||
"model_name",
|
||||
get_batch_model_names(),
|
||||
|
|
|
|||
340
tests/proxy_unit_tests/test_check_batch_cost.py
Normal file
340
tests/proxy_unit_tests/test_check_batch_cost.py
Normal file
|
|
@ -0,0 +1,340 @@
|
|||
"""
|
||||
Unit tests for CheckBatchCost class.
|
||||
Covers: stale-row cleanup (file_purpose scoping), paginated find_many,
|
||||
and the batch_processed-column fallback query.
|
||||
"""
|
||||
|
||||
from unittest.mock import AsyncMock, MagicMock, patch
|
||||
|
||||
import pytest
|
||||
|
||||
|
||||
class TestCheckBatchCost:
|
||||
"""Test suite for CheckBatchCost class"""
|
||||
|
||||
@pytest.fixture
|
||||
def mock_prisma_client(self):
|
||||
client = MagicMock()
|
||||
client.db = MagicMock()
|
||||
client.db.litellm_managedobjecttable = MagicMock()
|
||||
client.db.litellm_usertable = MagicMock()
|
||||
return client
|
||||
|
||||
@pytest.fixture
|
||||
def mock_proxy_logging_obj(self):
|
||||
return MagicMock()
|
||||
|
||||
@pytest.fixture
|
||||
def mock_llm_router(self):
|
||||
return MagicMock()
|
||||
|
||||
@pytest.fixture
|
||||
def check_batch_cost_instance(
|
||||
self, mock_proxy_logging_obj, mock_prisma_client, mock_llm_router
|
||||
):
|
||||
from litellm_enterprise.proxy.common_utils.check_batch_cost import CheckBatchCost
|
||||
|
||||
return CheckBatchCost(
|
||||
proxy_logging_obj=mock_proxy_logging_obj,
|
||||
prisma_client=mock_prisma_client,
|
||||
llm_router=mock_llm_router,
|
||||
)
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_cleanup_scoped_to_batch_file_purpose(
|
||||
self, check_batch_cost_instance, mock_prisma_client
|
||||
):
|
||||
"""_cleanup_stale_managed_objects scopes its update to file_purpose='batch' only."""
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=0
|
||||
)
|
||||
# Return empty so the main poll loop exits immediately
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
return_value=[]
|
||||
)
|
||||
|
||||
await check_batch_cost_instance.check_batch_cost()
|
||||
|
||||
calls = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args_list
|
||||
stale_call = calls[0]
|
||||
assert stale_call[1]["data"] == {"status": "stale_expired"}
|
||||
where = stale_call[1]["where"]
|
||||
assert where["file_purpose"] == "batch"
|
||||
assert "stale_expired" in where["status"]["not_in"]
|
||||
assert "created_at" in where
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_find_many_uses_pagination_and_excludes_stale(
|
||||
self, check_batch_cost_instance, mock_prisma_client
|
||||
):
|
||||
"""find_many is called with take, order, and all terminal statuses excluded."""
|
||||
from litellm.constants import MAX_OBJECTS_PER_POLL_CYCLE
|
||||
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=0
|
||||
)
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
return_value=[]
|
||||
)
|
||||
|
||||
await check_batch_cost_instance.check_batch_cost()
|
||||
|
||||
find_call = mock_prisma_client.db.litellm_managedobjecttable.find_many.call_args
|
||||
assert find_call[1]["take"] == MAX_OBJECTS_PER_POLL_CYCLE
|
||||
assert find_call[1]["order"] == {"created_at": "asc"}
|
||||
not_in = find_call[1]["where"]["status"]["not_in"]
|
||||
assert "stale_expired" in not_in
|
||||
assert "complete" in not_in
|
||||
assert "completed" in not_in
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_fallback_query_used_when_batch_processed_missing(
|
||||
self, check_batch_cost_instance, mock_prisma_client
|
||||
):
|
||||
"""Falls back to query without batch_processed when primary query raises."""
|
||||
from litellm.constants import MAX_OBJECTS_PER_POLL_CYCLE
|
||||
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=0
|
||||
)
|
||||
# First find_many (primary query) raises with a schema error; second (fallback) returns empty
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
side_effect=[Exception("column batch_processed does not exist"), []]
|
||||
)
|
||||
|
||||
await check_batch_cost_instance.check_batch_cost()
|
||||
|
||||
calls = mock_prisma_client.db.litellm_managedobjecttable.find_many.call_args_list
|
||||
assert len(calls) == 2
|
||||
fallback_where = calls[1][1]["where"]
|
||||
assert "batch_processed" not in fallback_where
|
||||
assert "stale_expired" in fallback_where["status"]["not_in"]
|
||||
assert calls[1][1]["take"] == MAX_OBJECTS_PER_POLL_CYCLE
|
||||
# Column absence is now cached — next call should go straight to fallback
|
||||
assert check_batch_cost_instance._has_batch_processed_column is False
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_column_absence_cached_across_cycles(
|
||||
self, check_batch_cost_instance, mock_prisma_client
|
||||
):
|
||||
"""After column absence is discovered, subsequent cycles skip the primary query entirely."""
|
||||
from litellm.constants import MAX_OBJECTS_PER_POLL_CYCLE
|
||||
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=0
|
||||
)
|
||||
# Simulate column already known absent from a previous cycle
|
||||
check_batch_cost_instance._has_batch_processed_column = False
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
return_value=[]
|
||||
)
|
||||
|
||||
await check_batch_cost_instance.check_batch_cost()
|
||||
|
||||
# Only one find_many call — the fallback directly, no primary query attempt
|
||||
assert mock_prisma_client.db.litellm_managedobjecttable.find_many.call_count == 1
|
||||
fallback_where = mock_prisma_client.db.litellm_managedobjecttable.find_many.call_args[1]["where"]
|
||||
assert "batch_processed" not in fallback_where
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_fallback_completion_update_omits_batch_processed(
|
||||
self, check_batch_cost_instance, mock_prisma_client, mock_llm_router
|
||||
):
|
||||
"""When batch_processed column is absent, completion update must not include it.
|
||||
|
||||
If it did, the update would fail silently, the job would never be marked done,
|
||||
and every subsequent poll cycle would re-log the cost (duplicate billing).
|
||||
"""
|
||||
from unittest.mock import patch
|
||||
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=0
|
||||
)
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update = AsyncMock()
|
||||
mock_prisma_client.db.litellm_usertable.find_unique = AsyncMock(
|
||||
return_value=None
|
||||
)
|
||||
|
||||
mock_job = MagicMock()
|
||||
mock_job.id = "job-fallback-1"
|
||||
mock_job.unified_object_id = "dW5pZmllZF9iYXRjaF9pZA=="
|
||||
mock_job.created_by = "user-1"
|
||||
|
||||
# Simulate column already known absent (e.g. discovered on a previous cycle)
|
||||
check_batch_cost_instance._has_batch_processed_column = False
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
return_value=[mock_job]
|
||||
)
|
||||
|
||||
# Build a fake batch response whose status triggers the completion branch
|
||||
mock_response = MagicMock()
|
||||
mock_response.status = "completed"
|
||||
mock_response.output_file_id = "file-output-123"
|
||||
mock_response.model_dump_json.return_value = '{"id":"batch-1","status":"completed"}'
|
||||
|
||||
mock_llm_router.aretrieve_batch = AsyncMock(return_value=mock_response)
|
||||
mock_llm_router.get_deployment_credentials_with_provider = MagicMock(
|
||||
return_value={"api_key": "sk-test"}
|
||||
)
|
||||
|
||||
mock_deployment = MagicMock()
|
||||
mock_deployment.litellm_params.custom_llm_provider = "openai"
|
||||
mock_deployment.litellm_params.model = "gpt-4"
|
||||
mock_deployment.model_info.model_dump.return_value = {}
|
||||
mock_llm_router.get_deployment = MagicMock(return_value=mock_deployment)
|
||||
|
||||
mock_file_content = MagicMock()
|
||||
mock_file_content.content = b'{"id":"req-1"}'
|
||||
|
||||
decoded_id = "llm_model_id,model-123;llm_batch_id,batch-456;"
|
||||
|
||||
with (
|
||||
patch(
|
||||
"litellm.proxy.openai_files_endpoints.common_utils._is_base64_encoded_unified_file_id",
|
||||
side_effect=[decoded_id, None],
|
||||
),
|
||||
patch(
|
||||
"litellm.proxy.openai_files_endpoints.common_utils.get_model_id_from_unified_batch_id",
|
||||
return_value="model-123",
|
||||
),
|
||||
patch(
|
||||
"litellm.proxy.openai_files_endpoints.common_utils.get_batch_id_from_unified_batch_id",
|
||||
return_value="batch-456",
|
||||
),
|
||||
patch(
|
||||
"litellm.files.main.afile_content",
|
||||
new_callable=AsyncMock,
|
||||
return_value=mock_file_content,
|
||||
),
|
||||
patch(
|
||||
"litellm.batches.batch_utils._get_file_content_as_dictionary",
|
||||
return_value=[{"id": "req-1"}],
|
||||
),
|
||||
patch(
|
||||
"litellm.batches.batch_utils.calculate_batch_cost_and_usage",
|
||||
new_callable=AsyncMock,
|
||||
return_value=(0.01, {"prompt_tokens": 10, "completion_tokens": 5}, ["gpt-4"]),
|
||||
),
|
||||
patch(
|
||||
"litellm.litellm_core_utils.get_llm_provider_logic.get_llm_provider",
|
||||
return_value=("gpt-4", "openai", None, None),
|
||||
),
|
||||
patch(
|
||||
"litellm.litellm_core_utils.litellm_logging.Logging"
|
||||
) as mock_logging_cls,
|
||||
):
|
||||
mock_logging_obj = MagicMock()
|
||||
mock_logging_obj.async_success_handler = AsyncMock()
|
||||
mock_logging_cls.return_value = mock_logging_obj
|
||||
|
||||
await check_batch_cost_instance.check_batch_cost()
|
||||
|
||||
# The update must have been called — this is the core assertion.
|
||||
assert mock_prisma_client.db.litellm_managedobjecttable.update.call_count == 1, (
|
||||
"Expected update() to be called exactly once for the completed job"
|
||||
)
|
||||
update_data = mock_prisma_client.db.litellm_managedobjecttable.update.call_args[1]["data"]
|
||||
assert "batch_processed" not in update_data, (
|
||||
"update() must NOT include batch_processed when column is absent"
|
||||
)
|
||||
assert update_data["status"] == "complete"
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_primary_path_completion_update_includes_batch_processed(
|
||||
self, check_batch_cost_instance, mock_prisma_client, mock_llm_router
|
||||
):
|
||||
"""When batch_processed column IS present, completion update must set it to True.
|
||||
|
||||
This is the symmetric counterpart to test_fallback_completion_update_omits_batch_processed
|
||||
and proves the conditional on _has_batch_processed_column governs the update data.
|
||||
"""
|
||||
from unittest.mock import patch
|
||||
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=0
|
||||
)
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update = AsyncMock()
|
||||
mock_prisma_client.db.litellm_usertable.find_unique = AsyncMock(
|
||||
return_value=None
|
||||
)
|
||||
|
||||
mock_job = MagicMock()
|
||||
mock_job.id = "job-primary-1"
|
||||
mock_job.unified_object_id = "dW5pZmllZF9iYXRjaF9pZA=="
|
||||
mock_job.created_by = "user-1"
|
||||
|
||||
assert check_batch_cost_instance._has_batch_processed_column is True
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
return_value=[mock_job]
|
||||
)
|
||||
|
||||
mock_response = MagicMock()
|
||||
mock_response.status = "completed"
|
||||
mock_response.output_file_id = "file-output-123"
|
||||
mock_response.model_dump_json.return_value = '{"id":"batch-1","status":"completed"}'
|
||||
|
||||
mock_llm_router.aretrieve_batch = AsyncMock(return_value=mock_response)
|
||||
mock_llm_router.get_deployment_credentials_with_provider = MagicMock(
|
||||
return_value={"api_key": "sk-test"}
|
||||
)
|
||||
|
||||
mock_deployment = MagicMock()
|
||||
mock_deployment.litellm_params.custom_llm_provider = "openai"
|
||||
mock_deployment.litellm_params.model = "gpt-4"
|
||||
mock_deployment.model_info.model_dump.return_value = {}
|
||||
mock_llm_router.get_deployment = MagicMock(return_value=mock_deployment)
|
||||
|
||||
mock_file_content = MagicMock()
|
||||
mock_file_content.content = b'{"id":"req-1"}'
|
||||
|
||||
decoded_id = "llm_model_id,model-123;llm_batch_id,batch-456;"
|
||||
|
||||
with (
|
||||
patch(
|
||||
"litellm.proxy.openai_files_endpoints.common_utils._is_base64_encoded_unified_file_id",
|
||||
side_effect=[decoded_id, None],
|
||||
),
|
||||
patch(
|
||||
"litellm.proxy.openai_files_endpoints.common_utils.get_model_id_from_unified_batch_id",
|
||||
return_value="model-123",
|
||||
),
|
||||
patch(
|
||||
"litellm.proxy.openai_files_endpoints.common_utils.get_batch_id_from_unified_batch_id",
|
||||
return_value="batch-456",
|
||||
),
|
||||
patch(
|
||||
"litellm.files.main.afile_content",
|
||||
new_callable=AsyncMock,
|
||||
return_value=mock_file_content,
|
||||
),
|
||||
patch(
|
||||
"litellm.batches.batch_utils._get_file_content_as_dictionary",
|
||||
return_value=[{"id": "req-1"}],
|
||||
),
|
||||
patch(
|
||||
"litellm.batches.batch_utils.calculate_batch_cost_and_usage",
|
||||
new_callable=AsyncMock,
|
||||
return_value=(0.01, {"prompt_tokens": 10, "completion_tokens": 5}, ["gpt-4"]),
|
||||
),
|
||||
patch(
|
||||
"litellm.litellm_core_utils.get_llm_provider_logic.get_llm_provider",
|
||||
return_value=("gpt-4", "openai", None, None),
|
||||
),
|
||||
patch(
|
||||
"litellm.litellm_core_utils.litellm_logging.Logging"
|
||||
) as mock_logging_cls,
|
||||
):
|
||||
mock_logging_obj = MagicMock()
|
||||
mock_logging_obj.async_success_handler = AsyncMock()
|
||||
mock_logging_cls.return_value = mock_logging_obj
|
||||
|
||||
await check_batch_cost_instance.check_batch_cost()
|
||||
|
||||
assert mock_prisma_client.db.litellm_managedobjecttable.update.call_count == 1, (
|
||||
"Expected update() to be called exactly once for the completed job"
|
||||
)
|
||||
update_data = mock_prisma_client.db.litellm_managedobjecttable.update.call_args[1]["data"]
|
||||
assert update_data["batch_processed"] is True, (
|
||||
"update() must include batch_processed=True when column is present"
|
||||
)
|
||||
assert update_data["status"] == "complete"
|
||||
|
|
@ -8,6 +8,7 @@ from unittest.mock import AsyncMock, MagicMock, Mock, patch
|
|||
|
||||
import pytest
|
||||
|
||||
from litellm.constants import MAX_OBJECTS_PER_POLL_CYCLE
|
||||
from litellm.types.llms.openai import ResponseAPIUsage, ResponsesAPIResponse
|
||||
|
||||
|
||||
|
|
@ -63,21 +64,46 @@ class TestCheckResponsesCost:
|
|||
self, check_responses_cost_instance, mock_prisma_client
|
||||
):
|
||||
"""Test check_responses_cost when there are no jobs to process"""
|
||||
# Mock empty job list
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
return_value=[]
|
||||
)
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=0
|
||||
)
|
||||
|
||||
await check_responses_cost_instance.check_responses_cost()
|
||||
|
||||
# Verify find_many was called with pagination params
|
||||
find_many_call = mock_prisma_client.db.litellm_managedobjecttable.find_many.call_args
|
||||
assert find_many_call[1]["where"] == {
|
||||
"status": {"in": ["queued", "in_progress"]},
|
||||
"file_purpose": "response",
|
||||
}
|
||||
assert find_many_call[1]["take"] == MAX_OBJECTS_PER_POLL_CYCLE
|
||||
assert find_many_call[1]["order"] == {"created_at": "asc"}
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_cleanup_stale_managed_objects(
|
||||
self, check_responses_cost_instance, mock_prisma_client
|
||||
):
|
||||
"""Stale rows (older than cutoff) are bulk-updated to stale_expired before polling."""
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=5
|
||||
)
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
return_value=[]
|
||||
)
|
||||
|
||||
# Should not raise any errors
|
||||
await check_responses_cost_instance.check_responses_cost()
|
||||
|
||||
# Verify find_many was called with correct parameters
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many.assert_called_once_with(
|
||||
where={
|
||||
"status": {"in": ["queued", "in_progress"]},
|
||||
"file_purpose": "response",
|
||||
}
|
||||
)
|
||||
# The first update_many call should be the stale-row cleanup scoped to "response"
|
||||
calls = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args_list
|
||||
stale_call = calls[0]
|
||||
assert stale_call[1]["data"] == {"status": "stale_expired"}
|
||||
where = stale_call[1]["where"]
|
||||
assert where["file_purpose"] == "response"
|
||||
assert "stale_expired" in where["status"]["not_in"]
|
||||
assert "created_at" in where
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_check_responses_cost_with_completed_response(
|
||||
|
|
@ -89,6 +115,7 @@ class TestCheckResponsesCost:
|
|||
mock_job.unified_object_id = "resp_test_123"
|
||||
mock_job.created_by = "test-user"
|
||||
mock_job.id = "job-123"
|
||||
mock_job.file_object = {"model": "gpt-4o", "id": "resp_test_123"}
|
||||
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
return_value=[mock_job]
|
||||
|
|
@ -108,8 +135,9 @@ class TestCheckResponsesCost:
|
|||
),
|
||||
)
|
||||
|
||||
# Mock update_many
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock()
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=0
|
||||
)
|
||||
|
||||
# Run the check with mocked litellm.aget_responses
|
||||
with patch("litellm.aget_responses", new_callable=AsyncMock) as mock_aget:
|
||||
|
|
@ -117,11 +145,12 @@ class TestCheckResponsesCost:
|
|||
|
||||
await check_responses_cost_instance.check_responses_cost()
|
||||
|
||||
# Verify the job was marked as completed
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many.assert_called_once()
|
||||
call_args = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args
|
||||
assert call_args[1]["data"]["status"] == "completed"
|
||||
assert call_args[1]["where"]["id"]["in"] == ["job-123"]
|
||||
# calls[0] = stale cleanup, calls[1] = job completion
|
||||
calls = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args_list
|
||||
assert len(calls) == 2
|
||||
completion_call = calls[1]
|
||||
assert completion_call[1]["data"]["status"] == "completed"
|
||||
assert completion_call[1]["where"]["id"]["in"] == ["job-123"]
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_check_responses_cost_with_failed_response(
|
||||
|
|
@ -133,6 +162,7 @@ class TestCheckResponsesCost:
|
|||
mock_job.unified_object_id = "resp_test_456"
|
||||
mock_job.created_by = "test-user"
|
||||
mock_job.id = "job-456"
|
||||
mock_job.file_object = {"model": "gpt-4o", "id": "resp_test_456"}
|
||||
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
return_value=[mock_job]
|
||||
|
|
@ -148,8 +178,9 @@ class TestCheckResponsesCost:
|
|||
usage=None,
|
||||
)
|
||||
|
||||
# Mock update_many
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock()
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=0
|
||||
)
|
||||
|
||||
# Run the check
|
||||
with patch("litellm.aget_responses", new_callable=AsyncMock) as mock_aget:
|
||||
|
|
@ -157,10 +188,10 @@ class TestCheckResponsesCost:
|
|||
|
||||
await check_responses_cost_instance.check_responses_cost()
|
||||
|
||||
# Verify the job was marked as completed (even though response failed)
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many.assert_called_once()
|
||||
call_args = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args
|
||||
assert call_args[1]["data"]["status"] == "completed"
|
||||
# calls[0] = stale cleanup, calls[1] = job completion
|
||||
calls = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args_list
|
||||
assert len(calls) == 2
|
||||
assert calls[1][1]["data"]["status"] == "completed"
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_check_responses_cost_with_cancelled_response(
|
||||
|
|
@ -172,6 +203,7 @@ class TestCheckResponsesCost:
|
|||
mock_job.unified_object_id = "resp_test_789"
|
||||
mock_job.created_by = "test-user"
|
||||
mock_job.id = "job-789"
|
||||
mock_job.file_object = {"model": "gpt-4o", "id": "resp_test_789"}
|
||||
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
return_value=[mock_job]
|
||||
|
|
@ -187,8 +219,9 @@ class TestCheckResponsesCost:
|
|||
usage=None,
|
||||
)
|
||||
|
||||
# Mock update_many
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock()
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=0
|
||||
)
|
||||
|
||||
# Run the check
|
||||
with patch("litellm.aget_responses", new_callable=AsyncMock) as mock_aget:
|
||||
|
|
@ -196,8 +229,10 @@ class TestCheckResponsesCost:
|
|||
|
||||
await check_responses_cost_instance.check_responses_cost()
|
||||
|
||||
# Verify the job was marked as completed
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many.assert_called_once()
|
||||
# calls[0] = stale cleanup, calls[1] = job completion
|
||||
calls = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args_list
|
||||
assert len(calls) == 2
|
||||
assert calls[1][1]["data"]["status"] == "completed"
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_check_responses_cost_with_in_progress_response(
|
||||
|
|
@ -209,6 +244,7 @@ class TestCheckResponsesCost:
|
|||
mock_job.unified_object_id = "resp_test_in_progress"
|
||||
mock_job.created_by = "test-user"
|
||||
mock_job.id = "job-in-progress"
|
||||
mock_job.file_object = {"model": "gpt-4o", "id": "resp_test_in_progress"}
|
||||
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
return_value=[mock_job]
|
||||
|
|
@ -224,8 +260,9 @@ class TestCheckResponsesCost:
|
|||
usage=None,
|
||||
)
|
||||
|
||||
# Mock update_many
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock()
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=0
|
||||
)
|
||||
|
||||
# Run the check
|
||||
with patch("litellm.aget_responses", new_callable=AsyncMock) as mock_aget:
|
||||
|
|
@ -233,8 +270,10 @@ class TestCheckResponsesCost:
|
|||
|
||||
await check_responses_cost_instance.check_responses_cost()
|
||||
|
||||
# Verify no updates were made (response still in progress)
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many.assert_not_called()
|
||||
# Only the stale-cleanup call should have fired — no completion update
|
||||
calls = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args_list
|
||||
assert len(calls) == 1
|
||||
assert calls[0][1]["data"] == {"status": "stale_expired"}
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_check_responses_cost_with_queued_response(
|
||||
|
|
@ -246,6 +285,7 @@ class TestCheckResponsesCost:
|
|||
mock_job.unified_object_id = "resp_test_queued"
|
||||
mock_job.created_by = "test-user"
|
||||
mock_job.id = "job-queued"
|
||||
mock_job.file_object = {"model": "gpt-4o", "id": "resp_test_queued"}
|
||||
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
return_value=[mock_job]
|
||||
|
|
@ -261,8 +301,9 @@ class TestCheckResponsesCost:
|
|||
usage=None,
|
||||
)
|
||||
|
||||
# Mock update_many
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock()
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=0
|
||||
)
|
||||
|
||||
# Run the check
|
||||
with patch("litellm.aget_responses", new_callable=AsyncMock) as mock_aget:
|
||||
|
|
@ -270,8 +311,10 @@ class TestCheckResponsesCost:
|
|||
|
||||
await check_responses_cost_instance.check_responses_cost()
|
||||
|
||||
# Verify no updates were made (response still queued)
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many.assert_not_called()
|
||||
# Only the stale-cleanup call should have fired — no completion update
|
||||
calls = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args_list
|
||||
assert len(calls) == 1
|
||||
assert calls[0][1]["data"] == {"status": "stale_expired"}
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_check_responses_cost_with_exception(
|
||||
|
|
@ -283,13 +326,15 @@ class TestCheckResponsesCost:
|
|||
mock_job.unified_object_id = "resp_test_error"
|
||||
mock_job.created_by = "test-user"
|
||||
mock_job.id = "job-error"
|
||||
mock_job.file_object = {"model": "gpt-4o", "id": "resp_test_error"}
|
||||
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
return_value=[mock_job]
|
||||
)
|
||||
|
||||
# Mock update_many
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock()
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=0
|
||||
)
|
||||
|
||||
# Run the check with mocked exception
|
||||
with patch(
|
||||
|
|
@ -300,8 +345,10 @@ class TestCheckResponsesCost:
|
|||
# Should not raise, just skip the job
|
||||
await check_responses_cost_instance.check_responses_cost()
|
||||
|
||||
# Verify no updates were made (job was skipped due to error)
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many.assert_not_called()
|
||||
# Only the stale-cleanup call should have fired — no completion update
|
||||
calls = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args_list
|
||||
assert len(calls) == 1
|
||||
assert calls[0][1]["data"] == {"status": "stale_expired"}
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_check_responses_cost_multiple_jobs(
|
||||
|
|
@ -313,16 +360,19 @@ class TestCheckResponsesCost:
|
|||
mock_job1.unified_object_id = "resp_test_1"
|
||||
mock_job1.created_by = "user1"
|
||||
mock_job1.id = "job-1"
|
||||
mock_job1.file_object = {"model": "gpt-4o", "id": "resp_test_1"}
|
||||
|
||||
mock_job2 = MagicMock()
|
||||
mock_job2.unified_object_id = "resp_test_2"
|
||||
mock_job2.created_by = "user2"
|
||||
mock_job2.id = "job-2"
|
||||
mock_job2.file_object = {"model": "gpt-4o", "id": "resp_test_2"}
|
||||
|
||||
mock_job3 = MagicMock()
|
||||
mock_job3.unified_object_id = "resp_test_3"
|
||||
mock_job3.created_by = "user3"
|
||||
mock_job3.id = "job-3"
|
||||
mock_job3.file_object = {"model": "gpt-4o", "id": "resp_test_3"}
|
||||
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
return_value=[mock_job1, mock_job2, mock_job3]
|
||||
|
|
@ -364,8 +414,9 @@ class TestCheckResponsesCost:
|
|||
),
|
||||
)
|
||||
|
||||
# Mock update_many
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock()
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=0
|
||||
)
|
||||
|
||||
# Run the check
|
||||
with patch("litellm.aget_responses", new_callable=AsyncMock) as mock_aget:
|
||||
|
|
@ -373,10 +424,41 @@ class TestCheckResponsesCost:
|
|||
|
||||
await check_responses_cost_instance.check_responses_cost()
|
||||
|
||||
# Verify only the 2 completed jobs were marked as complete
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many.assert_called_once()
|
||||
call_args = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args
|
||||
assert len(call_args[1]["where"]["id"]["in"]) == 2
|
||||
assert "job-1" in call_args[1]["where"]["id"]["in"]
|
||||
assert "job-3" in call_args[1]["where"]["id"]["in"]
|
||||
assert "job-2" not in call_args[1]["where"]["id"]["in"]
|
||||
# calls[0] = stale cleanup, calls[1] = completion of 2 finished jobs
|
||||
calls = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args_list
|
||||
assert len(calls) == 2
|
||||
completion_call = calls[1]
|
||||
assert len(completion_call[1]["where"]["id"]["in"]) == 2
|
||||
assert "job-1" in completion_call[1]["where"]["id"]["in"]
|
||||
assert "job-3" in completion_call[1]["where"]["id"]["in"]
|
||||
assert "job-2" not in completion_call[1]["where"]["id"]["in"]
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_check_responses_cost_no_model_in_file_object(
|
||||
self, check_responses_cost_instance, mock_prisma_client
|
||||
):
|
||||
"""When file_object has no 'model' key, model_name is None and metadata skips model fields."""
|
||||
mock_job = MagicMock()
|
||||
mock_job.unified_object_id = "resp_test_no_model"
|
||||
mock_job.created_by = "test-user"
|
||||
mock_job.id = "job-no-model"
|
||||
mock_job.file_object = {} # no "model" key → model_name=None branch
|
||||
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many = AsyncMock(
|
||||
return_value=[mock_job]
|
||||
)
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many = AsyncMock(
|
||||
return_value=0
|
||||
)
|
||||
|
||||
mock_response = MagicMock()
|
||||
mock_response.status = "completed"
|
||||
|
||||
with patch("litellm.aget_responses", new_callable=AsyncMock) as mock_aget:
|
||||
mock_aget.return_value = mock_response
|
||||
await check_responses_cost_instance.check_responses_cost()
|
||||
|
||||
# aget_responses should be called without model metadata
|
||||
call_kwargs = mock_aget.call_args[1]
|
||||
assert "model" not in call_kwargs.get("litellm_metadata", {})
|
||||
assert "model_group" not in call_kwargs.get("litellm_metadata", {})
|
||||
|
|
|
|||
|
|
@ -174,7 +174,6 @@ async def test_google_gemini_httpx_request_direct():
|
|||
],
|
||||
"role": "user"
|
||||
},
|
||||
"toolConfig": {"functionCallingConfig": {"mode": "ANY"}},
|
||||
"config": { # Note: already transformed from generationConfig
|
||||
"temperature": 0,
|
||||
"topP": 1,
|
||||
|
|
@ -241,7 +240,6 @@ async def test_google_gemini_httpx_request_direct():
|
|||
generate_content_provider_config=provider_config,
|
||||
generate_content_config_dict=sample_payload["config"],
|
||||
tools=None,
|
||||
tool_config=sample_payload["toolConfig"],
|
||||
custom_llm_provider="gemini",
|
||||
litellm_params=litellm_params,
|
||||
logging_obj=logging_obj,
|
||||
|
|
@ -267,7 +265,6 @@ async def test_google_gemini_httpx_request_direct():
|
|||
request_data = call_kwargs.get('json')
|
||||
if request_data:
|
||||
assert 'contents' in request_data, "Expected 'contents' in request data"
|
||||
assert request_data["toolConfig"] == sample_payload["toolConfig"]
|
||||
|
||||
# The config should be included in the request as generationConfig
|
||||
if 'generationConfig' in request_data:
|
||||
|
|
|
|||
|
|
@ -1944,12 +1944,12 @@ from litellm.proxy._types import LiteLLM_UserTable
|
|||
(
|
||||
"anthropic/*",
|
||||
{"model": "anthropic/*"},
|
||||
["anthropic/claude-3-5-haiku-20241022", "anthropic/claude-3-opus-20240229"],
|
||||
["anthropic/claude-haiku-4-5-20251001", "anthropic/claude-opus-4-6"],
|
||||
),
|
||||
(
|
||||
"vertex_ai/gemini-*",
|
||||
{"model": "vertex_ai/gemini-*"},
|
||||
["vertex_ai/gemini-1.5-flash", "vertex_ai/gemini-1.5-pro"],
|
||||
["vertex_ai/gemini-2.5-flash", "vertex_ai/gemini-2.5-pro"],
|
||||
),
|
||||
(
|
||||
"foo/*",
|
||||
|
|
|
|||
|
|
@ -1318,6 +1318,267 @@ class TestStreamingEventParsing:
|
|||
assert output_items["item_123"]["content"][0]["type"] == "text"
|
||||
|
||||
|
||||
def _make_sse_stream(events: list) -> Mock:
|
||||
"""Create a mock StreamingResponse with body_iterator from a list of event dicts."""
|
||||
|
||||
async def _body_iterator():
|
||||
for event in events:
|
||||
yield f"data: {json.dumps(event)}"
|
||||
yield "data: [DONE]"
|
||||
|
||||
mock_response = Mock()
|
||||
mock_response.body_iterator = _body_iterator()
|
||||
return mock_response
|
||||
|
||||
|
||||
def _make_background_streaming_kwargs(
|
||||
polling_id: str,
|
||||
polling_handler: ResponsePollingHandler,
|
||||
) -> dict:
|
||||
"""Build kwargs for background_streaming_task with all required mocks."""
|
||||
return dict(
|
||||
polling_id=polling_id,
|
||||
data={"model": "gpt-4o", "stream": False, "background": True},
|
||||
polling_handler=polling_handler,
|
||||
request=Mock(),
|
||||
fastapi_response=Mock(),
|
||||
user_api_key_dict=Mock(),
|
||||
general_settings={},
|
||||
llm_router=None,
|
||||
proxy_config=Mock(),
|
||||
proxy_logging_obj=Mock(),
|
||||
select_data_generator=Mock(),
|
||||
user_model=None,
|
||||
user_temperature=None,
|
||||
user_request_timeout=None,
|
||||
user_max_tokens=None,
|
||||
user_api_base=None,
|
||||
version=None,
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.xdist_group("heavy_imports")
|
||||
class TestBackgroundStreamingTerminalEvents:
|
||||
"""
|
||||
Integration tests that exercise background_streaming_task with mocked
|
||||
streaming responses, verifying the final update_state call for each
|
||||
terminal event type.
|
||||
"""
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_response_failed_sets_failed_status_and_error(self):
|
||||
"""Test that a response.failed stream event results in failed status with error"""
|
||||
from litellm.proxy.response_polling.background_streaming import (
|
||||
background_streaming_task,
|
||||
)
|
||||
|
||||
error_payload = {
|
||||
"type": "server_error",
|
||||
"message": "The model encountered an error",
|
||||
"code": "model_error",
|
||||
}
|
||||
events = [
|
||||
{"type": "response.in_progress"},
|
||||
{
|
||||
"type": "response.failed",
|
||||
"response": {
|
||||
"id": "resp_123",
|
||||
"status": "failed",
|
||||
"error": error_payload,
|
||||
"model": "gpt-4o",
|
||||
"output": [],
|
||||
},
|
||||
},
|
||||
]
|
||||
mock_response = _make_sse_stream(events)
|
||||
handler = AsyncMock(spec=ResponsePollingHandler)
|
||||
kwargs = _make_background_streaming_kwargs("poll_1", handler)
|
||||
|
||||
with patch(
|
||||
"litellm.proxy.response_polling.background_streaming.ProxyBaseLLMRequestProcessing"
|
||||
) as MockProcessor:
|
||||
MockProcessor.return_value.base_process_llm_request = AsyncMock(
|
||||
return_value=mock_response
|
||||
)
|
||||
await background_streaming_task(**kwargs)
|
||||
|
||||
# Find the final update_state call (last one)
|
||||
final_call = handler.update_state.call_args_list[-1]
|
||||
assert final_call.kwargs["status"] == "failed"
|
||||
assert final_call.kwargs["error"] == error_payload
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_response_incomplete_sets_incomplete_status_and_details(self):
|
||||
"""Test that a response.incomplete stream event results in incomplete status"""
|
||||
from litellm.proxy.response_polling.background_streaming import (
|
||||
background_streaming_task,
|
||||
)
|
||||
|
||||
events = [
|
||||
{"type": "response.in_progress"},
|
||||
{
|
||||
"type": "response.incomplete",
|
||||
"response": {
|
||||
"id": "resp_123",
|
||||
"status": "incomplete",
|
||||
"incomplete_details": {"reason": "max_output_tokens"},
|
||||
"usage": {"input_tokens": 10, "output_tokens": 4096},
|
||||
"model": "gpt-4o",
|
||||
"output": [{"id": "item_1", "type": "message"}],
|
||||
},
|
||||
},
|
||||
]
|
||||
mock_response = _make_sse_stream(events)
|
||||
handler = AsyncMock(spec=ResponsePollingHandler)
|
||||
kwargs = _make_background_streaming_kwargs("poll_2", handler)
|
||||
|
||||
with patch(
|
||||
"litellm.proxy.response_polling.background_streaming.ProxyBaseLLMRequestProcessing"
|
||||
) as MockProcessor:
|
||||
MockProcessor.return_value.base_process_llm_request = AsyncMock(
|
||||
return_value=mock_response
|
||||
)
|
||||
await background_streaming_task(**kwargs)
|
||||
|
||||
final_call = handler.update_state.call_args_list[-1]
|
||||
assert final_call.kwargs["status"] == "incomplete"
|
||||
assert final_call.kwargs["incomplete_details"] == {"reason": "max_output_tokens"}
|
||||
assert final_call.kwargs["usage"] == {"input_tokens": 10, "output_tokens": 4096}
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_response_cancelled_sets_cancelled_status(self):
|
||||
"""Test that a response.cancelled stream event results in cancelled status"""
|
||||
from litellm.proxy.response_polling.background_streaming import (
|
||||
background_streaming_task,
|
||||
)
|
||||
|
||||
events = [
|
||||
{"type": "response.in_progress"},
|
||||
{
|
||||
"type": "response.cancelled",
|
||||
"response": {
|
||||
"id": "resp_123",
|
||||
"status": "cancelled",
|
||||
"model": "gpt-4o",
|
||||
"output": [],
|
||||
},
|
||||
},
|
||||
]
|
||||
mock_response = _make_sse_stream(events)
|
||||
handler = AsyncMock(spec=ResponsePollingHandler)
|
||||
kwargs = _make_background_streaming_kwargs("poll_3", handler)
|
||||
|
||||
with patch(
|
||||
"litellm.proxy.response_polling.background_streaming.ProxyBaseLLMRequestProcessing"
|
||||
) as MockProcessor:
|
||||
MockProcessor.return_value.base_process_llm_request = AsyncMock(
|
||||
return_value=mock_response
|
||||
)
|
||||
await background_streaming_task(**kwargs)
|
||||
|
||||
final_call = handler.update_state.call_args_list[-1]
|
||||
assert final_call.kwargs["status"] == "cancelled"
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_response_completed_sets_completed_status(self):
|
||||
"""Test that a response.completed stream event results in completed status"""
|
||||
from litellm.proxy.response_polling.background_streaming import (
|
||||
background_streaming_task,
|
||||
)
|
||||
|
||||
events = [
|
||||
{"type": "response.in_progress"},
|
||||
{
|
||||
"type": "response.completed",
|
||||
"response": {
|
||||
"id": "resp_123",
|
||||
"status": "completed",
|
||||
"usage": {"input_tokens": 10, "output_tokens": 50},
|
||||
"model": "gpt-4o",
|
||||
"output": [{"id": "item_1", "type": "message"}],
|
||||
},
|
||||
},
|
||||
]
|
||||
mock_response = _make_sse_stream(events)
|
||||
handler = AsyncMock(spec=ResponsePollingHandler)
|
||||
kwargs = _make_background_streaming_kwargs("poll_4", handler)
|
||||
|
||||
with patch(
|
||||
"litellm.proxy.response_polling.background_streaming.ProxyBaseLLMRequestProcessing"
|
||||
) as MockProcessor:
|
||||
MockProcessor.return_value.base_process_llm_request = AsyncMock(
|
||||
return_value=mock_response
|
||||
)
|
||||
await background_streaming_task(**kwargs)
|
||||
|
||||
final_call = handler.update_state.call_args_list[-1]
|
||||
assert final_call.kwargs["status"] == "completed"
|
||||
assert final_call.kwargs["usage"] == {"input_tokens": 10, "output_tokens": 50}
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_fallback_status_derived_from_event_type_when_status_field_missing(self):
|
||||
"""Test that when the response body lacks a status field, the fallback
|
||||
is derived from the event type, not hardcoded to 'completed'."""
|
||||
from litellm.proxy.response_polling.background_streaming import (
|
||||
background_streaming_task,
|
||||
)
|
||||
|
||||
# response.incomplete event with NO status field in the response body
|
||||
events = [
|
||||
{"type": "response.in_progress"},
|
||||
{
|
||||
"type": "response.incomplete",
|
||||
"response": {
|
||||
"id": "resp_123",
|
||||
# "status" deliberately omitted
|
||||
"incomplete_details": {"reason": "max_output_tokens"},
|
||||
"model": "gpt-4o",
|
||||
"output": [],
|
||||
},
|
||||
},
|
||||
]
|
||||
mock_response = _make_sse_stream(events)
|
||||
handler = AsyncMock(spec=ResponsePollingHandler)
|
||||
kwargs = _make_background_streaming_kwargs("poll_5", handler)
|
||||
|
||||
with patch(
|
||||
"litellm.proxy.response_polling.background_streaming.ProxyBaseLLMRequestProcessing"
|
||||
) as MockProcessor:
|
||||
MockProcessor.return_value.base_process_llm_request = AsyncMock(
|
||||
return_value=mock_response
|
||||
)
|
||||
await background_streaming_task(**kwargs)
|
||||
|
||||
final_call = handler.update_state.call_args_list[-1]
|
||||
assert final_call.kwargs["status"] == "incomplete"
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_no_terminal_event_defaults_to_completed(self):
|
||||
"""Test that when no terminal event is received, status defaults to completed"""
|
||||
from litellm.proxy.response_polling.background_streaming import (
|
||||
background_streaming_task,
|
||||
)
|
||||
|
||||
# Stream with only in_progress, no terminal event
|
||||
events = [
|
||||
{"type": "response.in_progress"},
|
||||
]
|
||||
mock_response = _make_sse_stream(events)
|
||||
handler = AsyncMock(spec=ResponsePollingHandler)
|
||||
kwargs = _make_background_streaming_kwargs("poll_6", handler)
|
||||
|
||||
with patch(
|
||||
"litellm.proxy.response_polling.background_streaming.ProxyBaseLLMRequestProcessing"
|
||||
) as MockProcessor:
|
||||
MockProcessor.return_value.base_process_llm_request = AsyncMock(
|
||||
return_value=mock_response
|
||||
)
|
||||
await background_streaming_task(**kwargs)
|
||||
|
||||
final_call = handler.update_state.call_args_list[-1]
|
||||
assert final_call.kwargs["status"] == "completed"
|
||||
|
||||
|
||||
class TestEdgeCases:
|
||||
"""Test edge cases and error scenarios"""
|
||||
|
||||
|
|
|
|||
|
|
@ -2,6 +2,7 @@ import pytest
|
|||
import asyncio
|
||||
import aiohttp
|
||||
import json
|
||||
import time
|
||||
from httpx import AsyncClient
|
||||
from typing import Any, Optional
|
||||
from litellm._uuid import uuid
|
||||
|
|
@ -11,38 +12,26 @@ Tests to run
|
|||
|
||||
Basic Tests:
|
||||
1. Basic Spend Accuracy Test:
|
||||
- 1 Request costs $0.037
|
||||
- Make 12 requests
|
||||
- Expect the spend for each of the following to be 12 * $0.037
|
||||
Key: $0.444 (call /info endpoint for each object to validate)
|
||||
Team: $0.444
|
||||
User: $0.444
|
||||
Org: $0.444
|
||||
End User: $0.444
|
||||
- Make 1 calibration request, poll for spend to derive SPEND_PER_REQUEST
|
||||
- Make N-1 more requests (N total)
|
||||
- Expect the spend for each of the following to be N * SPEND_PER_REQUEST
|
||||
Key, Team, User, Org (call /info endpoint for each object to validate)
|
||||
|
||||
2. Long term spend accuracy test (with 2 bursts of requests)
|
||||
- 1 Request costs $0.037
|
||||
- Burst 1: 12 requests
|
||||
- Burst 2: 22 requests
|
||||
|
||||
- Expect the spend for each of the following to be (12 + 22) * $0.037
|
||||
Key: $1.296
|
||||
Team: $1.296
|
||||
User: $1.296
|
||||
Org: $1.296
|
||||
End User: $1.296
|
||||
- Burst 1: Make requests, derive SPEND_PER_REQUEST from first request
|
||||
- Burst 2: Make more requests
|
||||
- Verify total spend = (burst1 + burst2) * SPEND_PER_REQUEST
|
||||
|
||||
Additional Test Scenarios:
|
||||
|
||||
3. Concurrent Request Accuracy Test:
|
||||
- Make 20 concurrent requests
|
||||
- Verify total spend is 20 * $0.037
|
||||
- Check for race conditions in spend tracking
|
||||
|
||||
4. Error Case Test:
|
||||
- Make 10 successful requests ($0.037 each)
|
||||
- Make 10 successful requests
|
||||
- Make 5 failed requests
|
||||
- Verify spend is only counted for successful requests (10 * $0.037)
|
||||
- Verify spend is only counted for successful requests
|
||||
|
||||
5. Mixed Request Type Test:
|
||||
- Make different types of requests with varying costs
|
||||
|
|
@ -113,96 +102,64 @@ async def get_spend_info(session, entity_type: str, entity_id: str):
|
|||
return await response.json()
|
||||
|
||||
|
||||
async def poll_key_spend_until_nonzero(
|
||||
session, key: str, timeout: int = 120, interval: int = 10
|
||||
):
|
||||
"""Poll key spend until it becomes non-zero or timeout is reached."""
|
||||
start = time.time()
|
||||
while time.time() - start < timeout:
|
||||
key_info = await get_spend_info(session, "key", key)
|
||||
spend = key_info["info"]["spend"]
|
||||
if spend > 0:
|
||||
print(f"Key spend became non-zero ({spend}) after {time.time() - start:.1f}s")
|
||||
return spend
|
||||
print(f"Key spend still 0.0, waiting... ({time.time() - start:.1f}s elapsed)")
|
||||
await asyncio.sleep(interval)
|
||||
raise TimeoutError(
|
||||
f"Key spend remained 0.0 after {timeout}s — batch writer may not be running"
|
||||
)
|
||||
|
||||
|
||||
async def calibrate_spend_per_request(session, key: str, max_retries: int = 5):
|
||||
"""
|
||||
Make a single calibration request and poll for its spend to derive SPEND_PER_REQUEST.
|
||||
Fails fast with pytest.fail() if spend cannot be determined.
|
||||
"""
|
||||
response = await chat_completion(session, key)
|
||||
print(f"Calibration request completed: {response}")
|
||||
|
||||
for attempt in range(1, max_retries + 1):
|
||||
try:
|
||||
spend = await poll_key_spend_until_nonzero(
|
||||
session, key, timeout=120, interval=10
|
||||
)
|
||||
print(
|
||||
f"Calibrated SPEND_PER_REQUEST = {spend} "
|
||||
f"(attempt {attempt}/{max_retries})"
|
||||
)
|
||||
return spend
|
||||
except TimeoutError:
|
||||
if attempt < max_retries:
|
||||
print(
|
||||
f"Calibration attempt {attempt}/{max_retries} timed out, retrying..."
|
||||
)
|
||||
else:
|
||||
pytest.fail(
|
||||
f"Failed to calibrate SPEND_PER_REQUEST after {max_retries} attempts. "
|
||||
"The batch writer may not be running or the model may have 0 cost."
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_basic_spend_accuracy():
|
||||
"""
|
||||
Test basic spend accuracy across different entities:
|
||||
1. Create org, team, user, and key
|
||||
2. Make 12 requests at $0.037 each
|
||||
3. Verify spend accuracy for key, team, user, org, and end user
|
||||
2. Make 1 calibration request to derive SPEND_PER_REQUEST
|
||||
3. Make remaining requests (NUM_LLM_REQUESTS total)
|
||||
4. Verify spend accuracy for key, team, user, and org
|
||||
"""
|
||||
SPEND_PER_REQUEST = 3.75 * 10**-5
|
||||
NUM_LLM_REQUESTS = 20
|
||||
expected_spend = NUM_LLM_REQUESTS * SPEND_PER_REQUEST # 12 requests at $0.037 each
|
||||
|
||||
# Add tolerance constant at the top of the test
|
||||
TOLERANCE = 1e-10 # Small number to account for floating-point precision
|
||||
|
||||
async with aiohttp.ClientSession() as session:
|
||||
# Create organization
|
||||
org_response = await create_organization(
|
||||
session=session, organization_alias=f"test-org-{uuid.uuid4()}"
|
||||
)
|
||||
print("org_response: ", org_response)
|
||||
org_id = org_response["organization_id"]
|
||||
|
||||
# Create team under organization
|
||||
team_response = await create_team(session, org_id)
|
||||
print("team_response: ", team_response)
|
||||
team_id = team_response["team_id"]
|
||||
|
||||
# Create user
|
||||
user_response = await create_user(session, org_id)
|
||||
print("user_response: ", user_response)
|
||||
user_id = user_response["user_id"]
|
||||
|
||||
# Generate key
|
||||
key_response = await generate_key(session, user_id, team_id)
|
||||
print("key_response: ", key_response)
|
||||
key = key_response["key"]
|
||||
|
||||
# Make 12 requests
|
||||
for _ in range(NUM_LLM_REQUESTS):
|
||||
response = await chat_completion(session, key)
|
||||
print("response: ", response)
|
||||
|
||||
# wait 25 seconds for spend to be updated
|
||||
await asyncio.sleep(25)
|
||||
|
||||
# Get spend information for each entity
|
||||
key_info = await get_spend_info(session, "key", key)
|
||||
print("key_info: ", key_info)
|
||||
team_info = await get_spend_info(session, "team", team_id)
|
||||
print("team_info: ", team_info)
|
||||
user_info = await get_spend_info(session, "user", user_id)
|
||||
print("user_info: ", user_info)
|
||||
org_info = await get_spend_info(session, "organization", org_id)
|
||||
print("org_info: ", org_info)
|
||||
|
||||
# Verify spend for each entity
|
||||
assert (
|
||||
abs(key_info["info"]["spend"] - expected_spend) < TOLERANCE
|
||||
), f"Key spend {key_info['info']['spend']} does not match expected {expected_spend}"
|
||||
|
||||
assert (
|
||||
abs(user_info["user_info"]["spend"] - expected_spend) < TOLERANCE
|
||||
), f"User spend {user_info['info']['spend']} does not match expected {expected_spend}"
|
||||
|
||||
assert (
|
||||
abs(team_info["team_info"]["spend"] - expected_spend) < TOLERANCE
|
||||
), f"Team spend {team_info['team_info']['spend']} does not match expected {expected_spend}"
|
||||
|
||||
assert (
|
||||
abs(org_info["spend"] - expected_spend) < TOLERANCE
|
||||
), f"Organization spend {org_info['spend']} does not match expected {expected_spend}"
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_long_term_spend_accuracy_with_bursts():
|
||||
"""
|
||||
Test long-term spend accuracy with multiple bursts of requests:
|
||||
1. Create org, team, user, and key
|
||||
2. Burst 1: Make 12 requests
|
||||
3. Burst 2: Make 22 more requests
|
||||
4. Verify the total spend (34 requests) is tracked accurately across all entities
|
||||
"""
|
||||
SPEND_PER_REQUEST = 3.75 * 10**-5 # Cost per request
|
||||
BURST_1_REQUESTS = 22 # Number of requests in first burst
|
||||
BURST_2_REQUESTS = 12 # Number of requests in second burst
|
||||
TOTAL_REQUESTS = BURST_1_REQUESTS + BURST_2_REQUESTS
|
||||
expected_spend = TOTAL_REQUESTS * SPEND_PER_REQUEST
|
||||
|
||||
# Tolerance for floating-point comparison
|
||||
TOLERANCE = 1e-10
|
||||
|
||||
async with aiohttp.ClientSession() as session:
|
||||
|
|
@ -228,27 +185,143 @@ async def test_long_term_spend_accuracy_with_bursts():
|
|||
print("key_response: ", key_response)
|
||||
key = key_response["key"]
|
||||
|
||||
# First burst: 12 requests
|
||||
print(f"Starting first burst of {BURST_1_REQUESTS} requests...")
|
||||
for i in range(BURST_1_REQUESTS):
|
||||
response = await chat_completion(session, key)
|
||||
print(f"Burst 1 - Request {i+1}/{BURST_1_REQUESTS} completed")
|
||||
# Calibrate: make 1 request and derive SPEND_PER_REQUEST
|
||||
spend_per_request = await calibrate_spend_per_request(session, key)
|
||||
expected_spend = NUM_LLM_REQUESTS * spend_per_request
|
||||
print(f"SPEND_PER_REQUEST={spend_per_request}, expected_spend={expected_spend}")
|
||||
|
||||
# Wait for spend to be updated
|
||||
await asyncio.sleep(15)
|
||||
# Make remaining requests (1 already made during calibration)
|
||||
for i in range(NUM_LLM_REQUESTS - 1):
|
||||
response = await chat_completion(session, key)
|
||||
print(f"Request {i + 2}/{NUM_LLM_REQUESTS} completed")
|
||||
|
||||
# Poll until batch writer has flushed all spend
|
||||
start = time.time()
|
||||
while time.time() - start < 120:
|
||||
key_info = await get_spend_info(session, "key", key)
|
||||
current_spend = key_info["info"]["spend"]
|
||||
if abs(current_spend - expected_spend) < TOLERANCE:
|
||||
print(f"Key spend reached expected {expected_spend} after {time.time() - start:.1f}s")
|
||||
break
|
||||
print(f"Key spend {current_spend}, expected {expected_spend}, waiting...")
|
||||
await asyncio.sleep(10)
|
||||
|
||||
# Allow extra time for all entity spend aggregations to complete
|
||||
await asyncio.sleep(5)
|
||||
|
||||
# Get spend information for each entity
|
||||
key_info = await get_spend_info(session, "key", key)
|
||||
print("key_info: ", key_info)
|
||||
team_info = await get_spend_info(session, "team", team_id)
|
||||
print("team_info: ", team_info)
|
||||
user_info = await get_spend_info(session, "user", user_id)
|
||||
print("user_info: ", user_info)
|
||||
org_info = await get_spend_info(session, "organization", org_id)
|
||||
print("org_info: ", org_info)
|
||||
|
||||
# Verify spend for each entity
|
||||
assert (
|
||||
abs(key_info["info"]["spend"] - expected_spend) < TOLERANCE
|
||||
), f"Key spend {key_info['info']['spend']} does not match expected {expected_spend}"
|
||||
|
||||
assert (
|
||||
abs(user_info["user_info"]["spend"] - expected_spend) < TOLERANCE
|
||||
), f"User spend {user_info['user_info']['spend']} does not match expected {expected_spend}"
|
||||
|
||||
assert (
|
||||
abs(team_info["team_info"]["spend"] - expected_spend) < TOLERANCE
|
||||
), f"Team spend {team_info['team_info']['spend']} does not match expected {expected_spend}"
|
||||
|
||||
assert (
|
||||
abs(org_info["spend"] - expected_spend) < TOLERANCE
|
||||
), f"Organization spend {org_info['spend']} does not match expected {expected_spend}"
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_long_term_spend_accuracy_with_bursts():
|
||||
"""
|
||||
Test long-term spend accuracy with multiple bursts of requests:
|
||||
1. Create org, team, user, and key
|
||||
2. Calibrate SPEND_PER_REQUEST from first request
|
||||
3. Burst 1: Make remaining requests
|
||||
4. Burst 2: Make more requests
|
||||
5. Verify the total spend is tracked accurately across all entities
|
||||
"""
|
||||
BURST_1_REQUESTS = 22
|
||||
BURST_2_REQUESTS = 12
|
||||
TOTAL_REQUESTS = BURST_1_REQUESTS + BURST_2_REQUESTS
|
||||
TOLERANCE = 1e-10
|
||||
|
||||
async with aiohttp.ClientSession() as session:
|
||||
# Create organization
|
||||
org_response = await create_organization(
|
||||
session=session, organization_alias=f"test-org-{uuid.uuid4()}"
|
||||
)
|
||||
print("org_response: ", org_response)
|
||||
org_id = org_response["organization_id"]
|
||||
|
||||
# Create team under organization
|
||||
team_response = await create_team(session, org_id)
|
||||
print("team_response: ", team_response)
|
||||
team_id = team_response["team_id"]
|
||||
|
||||
# Create user
|
||||
user_response = await create_user(session, org_id)
|
||||
print("user_response: ", user_response)
|
||||
user_id = user_response["user_id"]
|
||||
|
||||
# Generate key
|
||||
key_response = await generate_key(session, user_id, team_id)
|
||||
print("key_response: ", key_response)
|
||||
key = key_response["key"]
|
||||
|
||||
# Calibrate: make 1 request and derive SPEND_PER_REQUEST
|
||||
spend_per_request = await calibrate_spend_per_request(session, key)
|
||||
expected_spend = TOTAL_REQUESTS * spend_per_request
|
||||
print(f"SPEND_PER_REQUEST={spend_per_request}, expected_spend={expected_spend}")
|
||||
|
||||
# First burst: remaining requests (1 already made during calibration)
|
||||
print(f"Starting first burst ({BURST_1_REQUESTS - 1} remaining requests)...")
|
||||
for i in range(BURST_1_REQUESTS - 1):
|
||||
response = await chat_completion(session, key)
|
||||
print(f"Burst 1 - Request {i + 2}/{BURST_1_REQUESTS} completed")
|
||||
|
||||
# Poll until batch writer has flushed burst 1 spend
|
||||
burst_1_expected = BURST_1_REQUESTS * spend_per_request
|
||||
start = time.time()
|
||||
while time.time() - start < 120:
|
||||
key_info_check = await get_spend_info(session, "key", key)
|
||||
current_spend = key_info_check["info"]["spend"]
|
||||
if abs(current_spend - burst_1_expected) < TOLERANCE:
|
||||
print(f"Burst 1 spend reached expected {burst_1_expected} after {time.time() - start:.1f}s")
|
||||
break
|
||||
print(f"Key spend {current_spend}, expected {burst_1_expected}, waiting...")
|
||||
await asyncio.sleep(10)
|
||||
|
||||
# Check intermediate spend
|
||||
intermediate_key_info = await get_spend_info(session, "key", key)
|
||||
print(f"After Burst 1 - Key spend: {intermediate_key_info['info']['spend']}")
|
||||
|
||||
# Second burst: 22 requests
|
||||
# Second burst
|
||||
print(f"Starting second burst of {BURST_2_REQUESTS} requests...")
|
||||
for i in range(BURST_2_REQUESTS):
|
||||
response = await chat_completion(session, key)
|
||||
print(f"Burst 2 - Request {i+1}/{BURST_2_REQUESTS} completed")
|
||||
print(f"Burst 2 - Request {i + 1}/{BURST_2_REQUESTS} completed")
|
||||
|
||||
# Wait for spend to be updated
|
||||
await asyncio.sleep(15)
|
||||
# Poll until key spend reflects burst 2
|
||||
burst_1_spend = intermediate_key_info["info"]["spend"]
|
||||
start = time.time()
|
||||
while time.time() - start < 120:
|
||||
key_info_check = await get_spend_info(session, "key", key)
|
||||
current_spend = key_info_check["info"]["spend"]
|
||||
if current_spend > burst_1_spend:
|
||||
print(f"Key spend increased to {current_spend} after {time.time() - start:.1f}s")
|
||||
break
|
||||
print(f"Key spend still {current_spend}, waiting for burst 2 flush...")
|
||||
await asyncio.sleep(10)
|
||||
|
||||
# Allow extra time for all entity spend aggregations
|
||||
await asyncio.sleep(5)
|
||||
|
||||
# Get final spend information for each entity
|
||||
key_info = await get_spend_info(session, "key", key)
|
||||
|
|
|
|||
|
|
@ -1390,6 +1390,8 @@ def test_apply_patch_tool_call_converted_to_chat_completion_tool_call():
|
|||
but the bridge silently dropped it (or raised an error), while the
|
||||
native litellm.responses() path worked correctly.
|
||||
"""
|
||||
pytest.importorskip("openai.types.responses.response_apply_patch_tool_call")
|
||||
|
||||
import json
|
||||
from unittest.mock import Mock
|
||||
|
||||
|
|
|
|||
|
|
@ -1,13 +1,24 @@
|
|||
#!/usr/bin/env python3
|
||||
"""Tests for Google GenAI main entrypoints."""
|
||||
|
||||
"""
|
||||
Test to verify the Google GenAI generate_content adapter functionality
|
||||
"""
|
||||
import json
|
||||
import os
|
||||
import sys
|
||||
from unittest.mock import AsyncMock, MagicMock, patch
|
||||
|
||||
import pytest
|
||||
|
||||
sys.path.insert(0, os.path.abspath("../../.."))
|
||||
sys.path.insert(
|
||||
0, os.path.abspath("../../..")
|
||||
) # Adds the parent directory to the system path
|
||||
|
||||
import json
|
||||
import os
|
||||
import sys
|
||||
|
||||
import pytest
|
||||
|
||||
import litellm
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
|
|
@ -15,6 +26,8 @@ async def test_agenerate_content_stream():
|
|||
"""
|
||||
Test that the agenerate_content_stream function works
|
||||
"""
|
||||
from unittest.mock import AsyncMock, patch
|
||||
|
||||
from litellm.google_genai.main import (
|
||||
agenerate_content_stream,
|
||||
base_llm_http_handler,
|
||||
|
|
@ -23,40 +36,10 @@ async def test_agenerate_content_stream():
|
|||
with patch.object(
|
||||
base_llm_http_handler, "generate_content_handler", new=AsyncMock()
|
||||
) as mock_post:
|
||||
await agenerate_content_stream(
|
||||
result = await agenerate_content_stream(
|
||||
model="gemini/gemini-2.0-flash-001",
|
||||
contents="Hello, world!",
|
||||
stream=True,
|
||||
)
|
||||
mock_post.assert_called_once()
|
||||
assert mock_post.call_args.kwargs["stream"] is True
|
||||
|
||||
|
||||
def test_generate_content_stream_forwards_system_instruction():
|
||||
"""Test that generate_content_stream forwards systemInstruction and toolConfig."""
|
||||
from litellm.google_genai.main import (
|
||||
base_llm_http_handler,
|
||||
generate_content_stream,
|
||||
)
|
||||
|
||||
mock_response = MagicMock()
|
||||
tool_config = {"functionCallingConfig": {"mode": "ANY"}}
|
||||
|
||||
with patch.object(
|
||||
base_llm_http_handler, "generate_content_handler", return_value=mock_response
|
||||
) as mock_post:
|
||||
result = generate_content_stream(
|
||||
model="gemini/gemini-2.0-flash-001",
|
||||
contents="Hello, world!",
|
||||
stream=True,
|
||||
systemInstruction={"parts": [{"text": "You are helpful"}]},
|
||||
toolConfig=tool_config,
|
||||
)
|
||||
|
||||
assert result is mock_response
|
||||
mock_post.assert_called_once()
|
||||
assert mock_post.call_args.kwargs["stream"] is True
|
||||
assert mock_post.call_args.kwargs["tool_config"] == tool_config
|
||||
assert mock_post.call_args.kwargs["system_instruction"] == {
|
||||
"parts": [{"text": "You are helpful"}]
|
||||
}
|
||||
mock_post.call_args.kwargs["stream"] == True
|
||||
|
|
|
|||
|
|
@ -12,9 +12,6 @@ sys.path.insert(
|
|||
import pytest
|
||||
|
||||
from litellm.llms.gemini.google_genai.transformation import GoogleGenAIConfig
|
||||
from litellm.llms.vertex_ai.google_genai.transformation import (
|
||||
VertexAIGoogleGenAIConfig,
|
||||
)
|
||||
from litellm.responses.litellm_completion_transformation.transformation import (
|
||||
LiteLLMCompletionResponsesConfig,
|
||||
)
|
||||
|
|
@ -176,26 +173,6 @@ def test_map_generate_content_optional_params_response_mime_type():
|
|||
assert "responseJsonSchema" in result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"config_cls",
|
||||
[GoogleGenAIConfig, VertexAIGoogleGenAIConfig],
|
||||
)
|
||||
def test_transform_generate_content_request_preserves_tool_config(config_cls):
|
||||
config = config_cls()
|
||||
tool_config = {"functionCallingConfig": {"mode": "ANY"}}
|
||||
|
||||
result = config.transform_generate_content_request(
|
||||
model="gemini-3-flash-preview",
|
||||
contents=[{"role": "user", "parts": [{"text": "hello"}]}],
|
||||
tools=[{"functionDeclarations": [{"name": "execute_command"}]}],
|
||||
tool_config=tool_config,
|
||||
generate_content_config_dict={"temperature": 1},
|
||||
system_instruction={"parts": [{"text": "system"}]},
|
||||
)
|
||||
|
||||
assert result["toolConfig"] == tool_config
|
||||
|
||||
|
||||
def test_responses_api_reasoning_dict_format():
|
||||
"""Test that reasoning parameter with dict format is mapped to reasoning_effort"""
|
||||
from litellm.types.llms.openai import ResponsesAPIOptionalRequestParams
|
||||
|
|
@ -297,7 +274,6 @@ def test_transform_generate_content_request_with_system_instruction():
|
|||
model="gemini-3-flash-preview",
|
||||
contents=contents,
|
||||
tools=None,
|
||||
tool_config=None,
|
||||
generate_content_config_dict=generate_content_config_dict,
|
||||
system_instruction=system_instruction,
|
||||
)
|
||||
|
|
@ -329,7 +305,6 @@ def test_transform_generate_content_request_without_system_instruction():
|
|||
model="gemini-3-flash-preview",
|
||||
contents=contents,
|
||||
tools=None,
|
||||
tool_config=None,
|
||||
generate_content_config_dict=generate_content_config_dict,
|
||||
system_instruction=None,
|
||||
)
|
||||
|
|
@ -381,7 +356,6 @@ def test_transform_generate_content_request_system_instruction_with_tools():
|
|||
model="gemini-3-flash-preview",
|
||||
contents=contents,
|
||||
tools=tools,
|
||||
tool_config=None,
|
||||
generate_content_config_dict=generate_content_config_dict,
|
||||
system_instruction=system_instruction,
|
||||
)
|
||||
|
|
|
|||
|
|
@ -9,6 +9,7 @@ from unittest.mock import AsyncMock, MagicMock, Mock, patch
|
|||
|
||||
import pytest
|
||||
|
||||
from litellm.constants import MAX_OBJECTS_PER_POLL_CYCLE
|
||||
from litellm.types.llms.openai import ResponseAPIUsage, ResponsesAPIResponse
|
||||
|
||||
|
||||
|
|
@ -336,12 +337,14 @@ class TestCheckResponsesCost:
|
|||
# Should not raise any errors
|
||||
await checker.check_responses_cost()
|
||||
|
||||
# Verify find_many was called with correct parameters
|
||||
# Verify find_many was called with correct parameters (includes pagination)
|
||||
mock_prisma_client.db.litellm_managedobjecttable.find_many.assert_called_once_with(
|
||||
where={
|
||||
"status": {"in": ["queued", "in_progress"]},
|
||||
"file_purpose": "response",
|
||||
}
|
||||
},
|
||||
take=MAX_OBJECTS_PER_POLL_CYCLE,
|
||||
order={"created_at": "asc"},
|
||||
)
|
||||
|
||||
@pytest.mark.asyncio
|
||||
|
|
@ -394,12 +397,15 @@ class TestCheckResponsesCost:
|
|||
await checker.check_responses_cost()
|
||||
|
||||
# Verify update_many was called to mark job as completed
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many.assert_called_once()
|
||||
call_args = (
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args
|
||||
)
|
||||
assert call_args[1]["where"]["id"]["in"] == ["job-123"]
|
||||
assert call_args[1]["data"]["status"] == "completed"
|
||||
# (stale cleanup also calls update_many, so check the specific completion call)
|
||||
update_many_calls = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args_list
|
||||
completion_calls = [
|
||||
c for c in update_many_calls
|
||||
if c.kwargs.get("where", {}).get("id") is not None
|
||||
]
|
||||
assert len(completion_calls) == 1
|
||||
assert completion_calls[0].kwargs["where"]["id"]["in"] == ["job-123"]
|
||||
assert completion_calls[0].kwargs["data"]["status"] == "completed"
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_check_responses_cost_with_failed_job(
|
||||
|
|
@ -443,7 +449,13 @@ class TestCheckResponsesCost:
|
|||
await checker.check_responses_cost()
|
||||
|
||||
# Verify job was marked as completed even though it failed
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many.assert_called_once()
|
||||
# (stale cleanup also calls update_many, so check the specific completion call)
|
||||
update_many_calls = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args_list
|
||||
completion_calls = [
|
||||
c for c in update_many_calls
|
||||
if c.kwargs.get("where", {}).get("id") is not None
|
||||
]
|
||||
assert len(completion_calls) == 1
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_check_responses_cost_with_in_progress_job(
|
||||
|
|
@ -486,8 +498,14 @@ class TestCheckResponsesCost:
|
|||
|
||||
await checker.check_responses_cost()
|
||||
|
||||
# Verify update_many was NOT called (job still in progress)
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many.assert_not_called()
|
||||
# Verify no completion update_many was called (job still in progress)
|
||||
# (stale cleanup may still call update_many, so filter for completion calls)
|
||||
update_many_calls = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args_list
|
||||
completion_calls = [
|
||||
c for c in update_many_calls
|
||||
if c.kwargs.get("where", {}).get("id") is not None
|
||||
]
|
||||
assert len(completion_calls) == 0
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_check_responses_cost_error_handling(
|
||||
|
|
@ -524,5 +542,11 @@ class TestCheckResponsesCost:
|
|||
# Should not raise - errors are caught and logged
|
||||
await checker.check_responses_cost()
|
||||
|
||||
# Verify update_many was NOT called (error occurred)
|
||||
mock_prisma_client.db.litellm_managedobjecttable.update_many.assert_not_called()
|
||||
# Verify no completion update_many was called (error occurred)
|
||||
# (stale cleanup may still call update_many, so filter for completion calls)
|
||||
update_many_calls = mock_prisma_client.db.litellm_managedobjecttable.update_many.call_args_list
|
||||
completion_calls = [
|
||||
c for c in update_many_calls
|
||||
if c.kwargs.get("where", {}).get("id") is not None
|
||||
]
|
||||
assert len(completion_calls) == 0
|
||||
|
|
|
|||
|
|
@ -1932,16 +1932,16 @@ def test_transform_request_uses_dynamic_max_tokens():
|
|||
|
||||
messages = [{"role": "user", "content": "Hello"}]
|
||||
|
||||
# Claude 3.5 model should get 8192 as default max_tokens
|
||||
# Claude 3.7 model should get 64000 as default max_tokens (from model_prices_and_context_window.json)
|
||||
result = config.transform_request(
|
||||
model="claude-3-5-sonnet-20241022",
|
||||
model="claude-3-7-sonnet-20250219",
|
||||
messages=messages,
|
||||
optional_params={}, # No max_tokens provided
|
||||
litellm_params={},
|
||||
headers={}
|
||||
)
|
||||
|
||||
assert result["max_tokens"] == 8192
|
||||
assert result["max_tokens"] == 64000
|
||||
|
||||
|
||||
def test_transform_request_respects_user_max_tokens():
|
||||
|
|
@ -1955,7 +1955,7 @@ def test_transform_request_respects_user_max_tokens():
|
|||
|
||||
# User provides explicit max_tokens=1000, should not be overridden
|
||||
result = config.transform_request(
|
||||
model="claude-3-5-sonnet-20241022",
|
||||
model="claude-3-7-sonnet-20250219",
|
||||
messages=messages,
|
||||
optional_params={"max_tokens": 1000},
|
||||
litellm_params={},
|
||||
|
|
|
|||
|
|
@ -282,6 +282,10 @@ class TestBlackForestLabsImageGenerationTransformation:
|
|||
raw_response=mock_response,
|
||||
model_response=model_response,
|
||||
logging_obj=self.logging_obj,
|
||||
request_data={},
|
||||
optional_params={},
|
||||
litellm_params={},
|
||||
encoding=None,
|
||||
)
|
||||
|
||||
assert len(result.data) == 1
|
||||
|
|
@ -306,6 +310,10 @@ class TestBlackForestLabsImageGenerationTransformation:
|
|||
raw_response=mock_response,
|
||||
model_response=model_response,
|
||||
logging_obj=self.logging_obj,
|
||||
request_data={},
|
||||
optional_params={},
|
||||
litellm_params={},
|
||||
encoding=None,
|
||||
)
|
||||
|
||||
assert len(result.data) == 2
|
||||
|
|
@ -329,6 +337,10 @@ class TestBlackForestLabsImageGenerationTransformation:
|
|||
raw_response=mock_response,
|
||||
model_response=model_response,
|
||||
logging_obj=self.logging_obj,
|
||||
request_data={},
|
||||
optional_params={},
|
||||
litellm_params={},
|
||||
encoding=None,
|
||||
)
|
||||
|
||||
def test_get_error_class(self):
|
||||
|
|
|
|||
0
tests/test_litellm/llms/gemini/__init__.py
Normal file
0
tests/test_litellm/llms/gemini/__init__.py
Normal file
0
tests/test_litellm/llms/gemini/image_edit/__init__.py
Normal file
0
tests/test_litellm/llms/gemini/image_edit/__init__.py
Normal file
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue