mirror of
https://github.com/BerriAI/litellm.git
synced 2026-09-21 00:21:49 +00:00
Merge branch 'BerriAI:main' into main
This commit is contained in:
 fzowl
GitHub
commit
5bb7394c93
1860 changed files with 201230 additions and 32887 deletions
|
|
@ -24,6 +24,40 @@ commands:
|
|||
cd enterprise
|
||||
python -m pip install -e .
|
||||
cd ..
|
||||
setup_litellm_test_deps:
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
- restore_cache:
|
||||
keys:
|
||||
- v2-litellm-deps-{{ checksum "requirements.txt" }}-{{ checksum ".circleci/config.yml" }}
|
||||
- v2-litellm-deps-
|
||||
- run:
|
||||
name: Install Dependencies
|
||||
command: |
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install -r requirements.txt
|
||||
pip install "pytest-mock==3.12.0"
|
||||
pip install "pytest==7.3.1"
|
||||
pip install "pytest-retry==1.6.3"
|
||||
pip install "pytest-cov==5.0.0"
|
||||
pip install "pytest-asyncio==0.21.1"
|
||||
pip install "respx==0.22.0"
|
||||
pip install "hypercorn==0.17.3"
|
||||
pip install "pydantic==2.10.2"
|
||||
pip install "mcp==1.10.1"
|
||||
pip install "requests-mock>=1.12.1"
|
||||
pip install "responses==0.25.7"
|
||||
pip install "pytest-xdist==3.6.1"
|
||||
pip install "pytest-timeout==2.2.0"
|
||||
pip install "semantic_router==0.1.10"
|
||||
pip install "fastapi-offline==1.7.3"
|
||||
pip install "a2a"
|
||||
- setup_litellm_enterprise_pip
|
||||
- save_cache:
|
||||
paths:
|
||||
- ~/.cache/pip
|
||||
key: v2-litellm-deps-{{ checksum "requirements.txt" }}-{{ checksum ".circleci/config.yml" }}
|
||||
|
||||
jobs:
|
||||
# Add Windows testing job
|
||||
|
|
@ -668,13 +702,16 @@ jobs:
|
|||
paths:
|
||||
- litellm_security_tests_coverage.xml
|
||||
- litellm_security_tests_coverage
|
||||
litellm_proxy_unit_testing: # Runs all tests with the "proxy", "key", "jwt" filenames
|
||||
# Split proxy unit tests into 3 jobs for faster execution and better debugging
|
||||
# test_key_generate_prisma runs separately without parallel execution to avoid event loop issues with logging worker
|
||||
litellm_proxy_unit_testing_key_generation:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
resource_class: large
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
|
|
@ -699,6 +736,114 @@ jobs:
|
|||
pip install "pytest-retry==1.6.3"
|
||||
pip install "pytest-asyncio==0.21.1"
|
||||
pip install "pytest-cov==5.0.0"
|
||||
pip install "pytest-timeout==2.2.0"
|
||||
pip install "pytest-forked==1.6.0"
|
||||
pip install "mypy==1.18.2"
|
||||
pip install "google-generativeai==0.3.2"
|
||||
pip install "google-cloud-aiplatform==1.43.0"
|
||||
pip install "google-genai==1.22.0"
|
||||
pip install pyarrow
|
||||
pip install "boto3==1.36.0"
|
||||
pip install "aioboto3==13.4.0"
|
||||
pip install langchain
|
||||
pip install lunary==0.2.5
|
||||
pip install "azure-identity==1.16.1"
|
||||
pip install "langfuse==2.59.7"
|
||||
pip install "logfire==0.29.0"
|
||||
pip install numpydoc
|
||||
pip install traceloop-sdk==0.21.1
|
||||
pip install opentelemetry-api==1.25.0
|
||||
pip install opentelemetry-sdk==1.25.0
|
||||
pip install opentelemetry-exporter-otlp==1.25.0
|
||||
pip install openai==1.100.1
|
||||
pip install prisma==0.11.0
|
||||
pip install "detect_secrets==1.5.0"
|
||||
pip install "httpx==0.24.1"
|
||||
pip install "respx==0.22.0"
|
||||
pip install fastapi
|
||||
pip install "gunicorn==21.2.0"
|
||||
pip install "anyio==4.2.0"
|
||||
pip install "aiodynamo==23.10.1"
|
||||
pip install "asyncio==3.4.3"
|
||||
pip install "apscheduler==3.10.4"
|
||||
pip install "PyGithub==1.59.1"
|
||||
pip install argon2-cffi
|
||||
pip install "pytest-mock==3.12.0"
|
||||
pip install python-multipart
|
||||
pip install google-cloud-aiplatform
|
||||
pip install prometheus-client==0.20.0
|
||||
pip install "pydantic==2.10.2"
|
||||
pip install "diskcache==5.6.1"
|
||||
pip install "Pillow==10.3.0"
|
||||
pip install "jsonschema==4.22.0"
|
||||
pip install "pytest-postgresql==7.0.1"
|
||||
pip install "fakeredis==2.28.1"
|
||||
- setup_litellm_enterprise_pip
|
||||
- save_cache:
|
||||
paths:
|
||||
- ./venv
|
||||
key: v1-dependencies-{{ checksum ".circleci/requirements.txt" }}
|
||||
- run:
|
||||
name: Run prisma ./docker/entrypoint.sh
|
||||
command: |
|
||||
set +e
|
||||
chmod +x docker/entrypoint.sh
|
||||
./docker/entrypoint.sh
|
||||
set -e
|
||||
- run:
|
||||
name: Run key generation tests (no parallel execution to avoid event loop issues)
|
||||
command: |
|
||||
pwd
|
||||
ls
|
||||
# Run without -n flag to avoid pytest-xdist event loop conflicts with logging worker
|
||||
python -m pytest tests/proxy_unit_tests/test_key_generate_prisma.py --cov=litellm --cov-report=xml --junitxml=test-results/junit-key-generation.xml --durations=10 --timeout=300 -vv --log-cli-level=INFO
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml litellm_proxy_unit_tests_key_generation_coverage.xml
|
||||
mv .coverage litellm_proxy_unit_tests_key_generation_coverage
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm_proxy_unit_tests_key_generation_coverage.xml
|
||||
- litellm_proxy_unit_tests_key_generation_coverage
|
||||
litellm_proxy_unit_testing_part1:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
resource_class: large
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
- run:
|
||||
name: Show git commit hash
|
||||
command: |
|
||||
echo "Git commit hash: $CIRCLE_SHA1"
|
||||
- run:
|
||||
name: Install PostgreSQL
|
||||
command: |
|
||||
sudo apt-get update
|
||||
sudo apt-get install -y postgresql-14 postgresql-contrib-14
|
||||
- restore_cache:
|
||||
keys:
|
||||
- v1-dependencies-{{ checksum ".circleci/requirements.txt" }}
|
||||
- run:
|
||||
name: Install Dependencies
|
||||
command: |
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install -r .circleci/requirements.txt
|
||||
pip install "pytest==7.3.1"
|
||||
pip install "pytest-retry==1.6.3"
|
||||
pip install "pytest-asyncio==0.21.1"
|
||||
pip install "pytest-cov==5.0.0"
|
||||
pip install "pytest-timeout==2.2.0"
|
||||
pip install "pytest-forked==1.6.0"
|
||||
pip install "mypy==1.18.2"
|
||||
pip install "google-generativeai==0.3.2"
|
||||
pip install "google-cloud-aiplatform==1.43.0"
|
||||
|
|
@ -752,28 +897,132 @@ jobs:
|
|||
chmod +x docker/entrypoint.sh
|
||||
./docker/entrypoint.sh
|
||||
set -e
|
||||
# Run pytest and generate JUnit XML report
|
||||
- run:
|
||||
name: Run tests
|
||||
name: Run proxy unit tests (part 1 - auth checks only, key generation in separate job)
|
||||
command: |
|
||||
pwd
|
||||
ls
|
||||
python -m pytest tests/proxy_unit_tests --cov=litellm --cov-report=xml -vv -x -v --junitxml=test-results/junit.xml --durations=5 -n 4
|
||||
# Run auth tests with parallel execution (test_key_generate_prisma moved to separate job to avoid event loop issues)
|
||||
python -m pytest tests/proxy_unit_tests/test_auth_checks.py tests/proxy_unit_tests/test_user_api_key_auth.py --cov=litellm --cov-report=xml --junitxml=test-results/junit-part1.xml --durations=10 -n 8 --timeout=300 -vv --log-cli-level=INFO
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml litellm_proxy_unit_tests_coverage.xml
|
||||
mv .coverage litellm_proxy_unit_tests_coverage
|
||||
# Store test results
|
||||
mv coverage.xml litellm_proxy_unit_tests_part1_coverage.xml
|
||||
mv .coverage litellm_proxy_unit_tests_part1_coverage
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm_proxy_unit_tests_coverage.xml
|
||||
- litellm_proxy_unit_tests_coverage
|
||||
- litellm_proxy_unit_tests_part1_coverage.xml
|
||||
- litellm_proxy_unit_tests_part1_coverage
|
||||
litellm_proxy_unit_testing_part2:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
resource_class: large
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
- run:
|
||||
name: Show git commit hash
|
||||
command: |
|
||||
echo "Git commit hash: $CIRCLE_SHA1"
|
||||
- run:
|
||||
name: Install PostgreSQL
|
||||
command: |
|
||||
sudo apt-get update
|
||||
sudo apt-get install -y postgresql-14 postgresql-contrib-14
|
||||
- restore_cache:
|
||||
keys:
|
||||
- v1-dependencies-{{ checksum ".circleci/requirements.txt" }}
|
||||
- run:
|
||||
name: Install Dependencies
|
||||
command: |
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install -r .circleci/requirements.txt
|
||||
pip install "pytest==7.3.1"
|
||||
pip install "pytest-retry==1.6.3"
|
||||
pip install "pytest-asyncio==0.21.1"
|
||||
pip install "pytest-cov==5.0.0"
|
||||
pip install "pytest-timeout==2.2.0"
|
||||
pip install "pytest-forked==1.6.0"
|
||||
pip install "mypy==1.18.2"
|
||||
pip install "google-generativeai==0.3.2"
|
||||
pip install "google-cloud-aiplatform==1.43.0"
|
||||
pip install "google-genai==1.22.0"
|
||||
pip install pyarrow
|
||||
pip install "boto3==1.36.0"
|
||||
pip install "aioboto3==13.4.0"
|
||||
pip install langchain
|
||||
pip install lunary==0.2.5
|
||||
pip install "azure-identity==1.16.1"
|
||||
pip install "langfuse==2.59.7"
|
||||
pip install "logfire==0.29.0"
|
||||
pip install numpydoc
|
||||
pip install traceloop-sdk==0.21.1
|
||||
pip install opentelemetry-api==1.25.0
|
||||
pip install opentelemetry-sdk==1.25.0
|
||||
pip install opentelemetry-exporter-otlp==1.25.0
|
||||
pip install openai==1.100.1
|
||||
pip install prisma==0.11.0
|
||||
pip install "detect_secrets==1.5.0"
|
||||
pip install "httpx==0.24.1"
|
||||
pip install "respx==0.22.0"
|
||||
pip install fastapi
|
||||
pip install "gunicorn==21.2.0"
|
||||
pip install "anyio==4.2.0"
|
||||
pip install "aiodynamo==23.10.1"
|
||||
pip install "asyncio==3.4.3"
|
||||
pip install "apscheduler==3.10.4"
|
||||
pip install "PyGithub==1.59.1"
|
||||
pip install argon2-cffi
|
||||
pip install "pytest-mock==3.12.0"
|
||||
pip install python-multipart
|
||||
pip install google-cloud-aiplatform
|
||||
pip install prometheus-client==0.20.0
|
||||
pip install "pydantic==2.10.2"
|
||||
pip install "diskcache==5.6.1"
|
||||
pip install "Pillow==10.3.0"
|
||||
pip install "jsonschema==4.22.0"
|
||||
pip install "pytest-postgresql==7.0.1"
|
||||
pip install "fakeredis==2.28.1"
|
||||
pip install "pytest-xdist==3.6.1"
|
||||
- setup_litellm_enterprise_pip
|
||||
- save_cache:
|
||||
paths:
|
||||
- ./venv
|
||||
key: v1-dependencies-{{ checksum ".circleci/requirements.txt" }}
|
||||
- run:
|
||||
name: Run prisma ./docker/entrypoint.sh
|
||||
command: |
|
||||
set +e
|
||||
chmod +x docker/entrypoint.sh
|
||||
./docker/entrypoint.sh
|
||||
set -e
|
||||
- run:
|
||||
name: Run proxy unit tests (part 2 - remaining tests)
|
||||
command: |
|
||||
pwd
|
||||
ls
|
||||
python -m pytest tests/proxy_unit_tests --ignore=tests/proxy_unit_tests/test_key_generate_prisma.py --ignore=tests/proxy_unit_tests/test_auth_checks.py --ignore=tests/proxy_unit_tests/test_user_api_key_auth.py --cov=litellm --cov-report=xml --junitxml=test-results/junit-part2.xml --durations=10 -n 8 --timeout=300 -vv --log-cli-level=INFO
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml litellm_proxy_unit_tests_part2_coverage.xml
|
||||
mv .coverage litellm_proxy_unit_tests_part2_coverage
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm_proxy_unit_tests_part2_coverage.xml
|
||||
- litellm_proxy_unit_tests_part2_coverage
|
||||
litellm_assistants_api_testing: # Runs all tests with the "assistants" keyword
|
||||
docker:
|
||||
- image: cimg/python:3.13.1
|
||||
|
|
@ -1128,59 +1377,89 @@ jobs:
|
|||
paths:
|
||||
- search_coverage.xml
|
||||
- search_coverage
|
||||
litellm_mapped_tests:
|
||||
# Split litellm_mapped_tests into 3 parallel jobs for 3x faster execution
|
||||
litellm_mapped_tests_proxy:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
|
||||
resource_class: xlarge
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
- setup_litellm_test_deps
|
||||
- run:
|
||||
name: Install Dependencies
|
||||
name: Run proxy tests
|
||||
command: |
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install -r requirements.txt
|
||||
pip install "pytest-mock==3.12.0"
|
||||
pip install "pytest==7.3.1"
|
||||
pip install "pytest-retry==1.6.3"
|
||||
pip install "pytest-cov==5.0.0"
|
||||
pip install "pytest-asyncio==0.21.1"
|
||||
pip install "respx==0.22.0"
|
||||
pip install "hypercorn==0.17.3"
|
||||
pip install "pydantic==2.10.2"
|
||||
pip install "mcp==1.10.1"
|
||||
pip install "requests-mock>=1.12.1"
|
||||
pip install "responses==0.25.7"
|
||||
pip install "pytest-xdist==3.6.1"
|
||||
pip install "semantic_router==0.1.10"
|
||||
pip install "fastapi-offline==1.7.3"
|
||||
- setup_litellm_enterprise_pip
|
||||
# Run pytest and generate JUnit XML report
|
||||
- run:
|
||||
name: Run litellm tests
|
||||
command: |
|
||||
pwd
|
||||
ls
|
||||
python -m pytest -vv tests/test_litellm --cov=litellm --cov-report=xml -v --junitxml=test-results/junit-litellm.xml --durations=10 -n 8
|
||||
prisma generate
|
||||
python -m pytest tests/test_litellm/proxy --cov=litellm --cov-report=xml --junitxml=test-results/junit-proxy.xml --durations=10 -n 16 --maxfail=5 --timeout=300 -vv --log-cli-level=WARNING
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml litellm_mapped_tests_coverage.xml
|
||||
mv .coverage litellm_mapped_tests_coverage
|
||||
|
||||
# Store test results
|
||||
mv coverage.xml litellm_proxy_tests_coverage.xml
|
||||
mv .coverage litellm_proxy_tests_coverage
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm_mapped_tests_coverage.xml
|
||||
- litellm_mapped_tests_coverage
|
||||
- litellm_proxy_tests_coverage.xml
|
||||
- litellm_proxy_tests_coverage
|
||||
litellm_mapped_tests_llms:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
resource_class: xlarge
|
||||
steps:
|
||||
- setup_litellm_test_deps
|
||||
- run:
|
||||
name: Run LLM provider tests
|
||||
command: |
|
||||
python -m pytest tests/test_litellm/llms --cov=litellm --cov-report=xml --junitxml=test-results/junit-llms.xml --durations=10 -n 16 --maxfail=5 --timeout=300 -vv --log-cli-level=WARNING
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml litellm_llms_tests_coverage.xml
|
||||
mv .coverage litellm_llms_tests_coverage
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm_llms_tests_coverage.xml
|
||||
- litellm_llms_tests_coverage
|
||||
litellm_mapped_tests_core:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
resource_class: xlarge
|
||||
steps:
|
||||
- setup_litellm_test_deps
|
||||
- run:
|
||||
name: Run core tests
|
||||
command: |
|
||||
python -m pytest tests/test_litellm --ignore=tests/test_litellm/proxy --ignore=tests/test_litellm/llms --cov=litellm --cov-report=xml --junitxml=test-results/junit-core.xml --durations=10 -n 16 --maxfail=5 --timeout=300 -vv --log-cli-level=WARNING
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml litellm_core_tests_coverage.xml
|
||||
mv .coverage litellm_core_tests_coverage
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm_core_tests_coverage.xml
|
||||
- litellm_core_tests_coverage
|
||||
litellm_mapped_enterprise_tests:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
|
|
@ -1447,7 +1726,7 @@ jobs:
|
|||
command: |
|
||||
pwd
|
||||
ls
|
||||
python -m pytest -vv tests/logging_callback_tests --cov=litellm --cov-report=xml -x -s -v --junitxml=test-results/junit.xml --durations=5
|
||||
python -m pytest -vv tests/logging_callback_tests --cov=litellm --cov-report=xml -s -v --junitxml=test-results/junit.xml --durations=5
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
|
|
@ -1508,7 +1787,7 @@ jobs:
|
|||
- audio_coverage
|
||||
installing_litellm_on_python:
|
||||
docker:
|
||||
- image: circleci/python:3.8
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
|
|
@ -1914,14 +2193,14 @@ jobs:
|
|||
sudo usermod -aG docker $USER
|
||||
docker version
|
||||
- run:
|
||||
name: Install Python 3.9
|
||||
name: Install Python 3.10
|
||||
command: |
|
||||
curl https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh --output miniconda.sh
|
||||
bash miniconda.sh -b -p $HOME/miniconda
|
||||
export PATH="$HOME/miniconda/bin:$PATH"
|
||||
conda init bash
|
||||
source ~/.bashrc
|
||||
conda create -n myenv python=3.9 -y
|
||||
conda create -n myenv python=3.10 -y
|
||||
conda activate myenv
|
||||
python --version
|
||||
- run:
|
||||
|
|
@ -2695,19 +2974,22 @@ jobs:
|
|||
sudo usermod -aG docker $USER
|
||||
docker version
|
||||
- run:
|
||||
name: Install Python 3.9
|
||||
name: Install Python 3.10
|
||||
command: |
|
||||
curl https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh --output miniconda.sh
|
||||
bash miniconda.sh -b -p $HOME/miniconda
|
||||
export PATH="$HOME/miniconda/bin:$PATH"
|
||||
conda init bash
|
||||
source ~/.bashrc
|
||||
conda create -n myenv python=3.9 -y
|
||||
conda create -n myenv python=3.10 -y
|
||||
conda activate myenv
|
||||
python --version
|
||||
- run:
|
||||
name: Install Dependencies
|
||||
command: |
|
||||
export PATH="$HOME/miniconda/bin:$PATH"
|
||||
source $HOME/miniconda/etc/profile.d/conda.sh
|
||||
conda activate myenv
|
||||
pip install "pytest==7.3.1"
|
||||
pip install "pytest-retry==1.6.3"
|
||||
pip install "pytest-asyncio==0.21.1"
|
||||
|
|
@ -2736,6 +3018,8 @@ jobs:
|
|||
pip install "langchain_mcp_adapters==0.0.5"
|
||||
pip install "langchain_openai==0.2.1"
|
||||
pip install "langgraph==0.3.18"
|
||||
pip install "fastuuid==0.13.5"
|
||||
pip install -r requirements.txt
|
||||
- run:
|
||||
name: Install dockerize
|
||||
command: |
|
||||
|
|
@ -2848,6 +3132,9 @@ jobs:
|
|||
- run:
|
||||
name: Run tests
|
||||
command: |
|
||||
export PATH="$HOME/miniconda/bin:$PATH"
|
||||
source $HOME/miniconda/etc/profile.d/conda.sh
|
||||
conda activate myenv
|
||||
pwd
|
||||
ls
|
||||
python -m pytest -vv tests/pass_through_tests/ -x --junitxml=test-results/junit.xml --durations=5
|
||||
|
|
@ -2878,7 +3165,7 @@ jobs:
|
|||
python -m venv venv
|
||||
. venv/bin/activate
|
||||
pip install coverage
|
||||
coverage combine llm_translation_coverage llm_responses_api_coverage ocr_coverage search_coverage mcp_coverage logging_coverage audio_coverage litellm_router_coverage local_testing_coverage litellm_assistants_api_coverage auth_ui_unit_tests_coverage langfuse_coverage caching_coverage litellm_proxy_unit_tests_coverage image_gen_coverage pass_through_unit_tests_coverage batches_coverage litellm_security_tests_coverage guardrails_coverage
|
||||
coverage combine llm_translation_coverage llm_responses_api_coverage ocr_coverage search_coverage mcp_coverage logging_coverage audio_coverage litellm_router_coverage local_testing_coverage litellm_assistants_api_coverage auth_ui_unit_tests_coverage langfuse_coverage caching_coverage litellm_proxy_unit_tests_part1_coverage litellm_proxy_unit_tests_part2_coverage image_gen_coverage pass_through_unit_tests_coverage batches_coverage litellm_security_tests_coverage guardrails_coverage litellm_mapped_tests_coverage
|
||||
coverage xml
|
||||
- codecov/upload:
|
||||
file: ./coverage.xml
|
||||
|
|
@ -3054,7 +3341,7 @@ jobs:
|
|||
python -m build
|
||||
twine upload --verbose dist/*
|
||||
|
||||
e2e_ui_testing:
|
||||
ui_build:
|
||||
machine:
|
||||
image: ubuntu-2204:2023.10.1
|
||||
resource_class: xlarge
|
||||
|
|
@ -3081,6 +3368,50 @@ jobs:
|
|||
|
||||
# Now source the build script
|
||||
source ./build_ui.sh
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm/proxy/_experimental/out
|
||||
|
||||
ui_unit_tests:
|
||||
machine:
|
||||
image: ubuntu-2204:2023.10.1
|
||||
resource_class: xlarge
|
||||
working_directory: ~/project
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
- run:
|
||||
name: Run UI unit tests (Vitest)
|
||||
command: |
|
||||
# Use Node 20 (several deps require >=20)
|
||||
export NVM_DIR="/opt/circleci/.nvm"
|
||||
source "$NVM_DIR/nvm.sh"
|
||||
nvm install 20
|
||||
nvm use 20
|
||||
|
||||
cd ui/litellm-dashboard
|
||||
# Remove node_modules and package-lock to ensure clean install (fixes optional deps issue)
|
||||
rm -rf node_modules package-lock.json
|
||||
npm install
|
||||
|
||||
# CI run, with both LCOV (Codecov) and HTML (artifact you can click)
|
||||
CI=true npm run test -- --run --coverage \
|
||||
--coverage.provider=v8 \
|
||||
--coverage.reporter=lcov \
|
||||
--coverage.reporter=html \
|
||||
--coverage.reportsDirectory=coverage/html
|
||||
|
||||
e2e_ui_testing:
|
||||
machine:
|
||||
image: ubuntu-2204:2023.10.1
|
||||
resource_class: xlarge
|
||||
working_directory: ~/project
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
- attach_workspace:
|
||||
at: ~/project
|
||||
- run:
|
||||
name: Upgrade Docker to v24.x (API 1.44+)
|
||||
command: |
|
||||
|
|
@ -3126,24 +3457,6 @@ jobs:
|
|||
name: Install Playwright Browsers
|
||||
command: |
|
||||
npx playwright install
|
||||
- run:
|
||||
name: Run UI unit tests (Vitest)
|
||||
command: |
|
||||
# Use Node 20 (several deps require >=20)
|
||||
export NVM_DIR="/opt/circleci/.nvm"
|
||||
source "$NVM_DIR/nvm.sh"
|
||||
nvm install 20
|
||||
nvm use 20
|
||||
|
||||
cd ui/litellm-dashboard
|
||||
npm ci || npm install
|
||||
|
||||
# CI run, with both LCOV (Codecov) and HTML (artifact you can click)
|
||||
CI=true npm run test -- --run --coverage \
|
||||
--coverage.provider=v8 \
|
||||
--coverage.reporter=lcov \
|
||||
--coverage.reporter=html \
|
||||
--coverage.reportsDirectory=coverage/html
|
||||
|
||||
- run:
|
||||
name: Build Docker image
|
||||
|
|
@ -3185,8 +3498,13 @@ jobs:
|
|||
command: |
|
||||
npx playwright test e2e_ui_tests/ --reporter=html --output=test-results
|
||||
no_output_timeout: 120m
|
||||
- store_test_results:
|
||||
- store_artifacts:
|
||||
path: test-results
|
||||
destination: playwright-results
|
||||
|
||||
- store_artifacts:
|
||||
path: playwright-report
|
||||
destination: playwright-report
|
||||
|
||||
test_nonroot_image:
|
||||
machine:
|
||||
|
|
@ -3300,7 +3618,19 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_proxy_unit_testing:
|
||||
- litellm_proxy_unit_testing_key_generation:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_proxy_unit_testing_part1:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_proxy_unit_testing_part2:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
|
|
@ -3336,6 +3666,20 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- ui_build:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- ui_unit_tests:
|
||||
requires:
|
||||
- ui_build
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- auth_ui_unit_tests:
|
||||
filters:
|
||||
branches:
|
||||
|
|
@ -3343,6 +3687,8 @@ workflows:
|
|||
- main
|
||||
- /litellm_.*/
|
||||
- e2e_ui_testing:
|
||||
requires:
|
||||
- ui_build
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
|
|
@ -3444,7 +3790,19 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_mapped_tests:
|
||||
- litellm_mapped_tests_proxy:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_mapped_tests_llms:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_mapped_tests_core:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
|
|
@ -3495,7 +3853,9 @@ workflows:
|
|||
- llm_responses_api_testing
|
||||
- ocr_testing
|
||||
- search_testing
|
||||
- litellm_mapped_tests
|
||||
- litellm_mapped_tests_proxy
|
||||
- litellm_mapped_tests_llms
|
||||
- litellm_mapped_tests_core
|
||||
- litellm_mapped_enterprise_tests
|
||||
- batches_testing
|
||||
- litellm_utils_testing
|
||||
|
|
@ -3506,7 +3866,9 @@ workflows:
|
|||
- litellm_router_testing
|
||||
- litellm_router_unit_testing
|
||||
- caching_unit_tests
|
||||
- litellm_proxy_unit_testing
|
||||
- litellm_proxy_unit_testing_key_generation
|
||||
- litellm_proxy_unit_testing_part1
|
||||
- litellm_proxy_unit_testing_part2
|
||||
- litellm_security_tests
|
||||
- langfuse_logging_unit_tests
|
||||
- local_testing
|
||||
|
|
@ -3560,7 +3922,9 @@ workflows:
|
|||
- llm_responses_api_testing
|
||||
- ocr_testing
|
||||
- search_testing
|
||||
- litellm_mapped_tests
|
||||
- litellm_mapped_tests_proxy
|
||||
- litellm_mapped_tests_llms
|
||||
- litellm_mapped_tests_core
|
||||
- litellm_mapped_enterprise_tests
|
||||
- batches_testing
|
||||
- litellm_utils_testing
|
||||
|
|
@ -3576,7 +3940,9 @@ workflows:
|
|||
- auth_ui_unit_tests
|
||||
- db_migration_disable_update_check
|
||||
- e2e_ui_testing
|
||||
- litellm_proxy_unit_testing
|
||||
- litellm_proxy_unit_testing_key_generation
|
||||
- litellm_proxy_unit_testing_part1
|
||||
- litellm_proxy_unit_testing_part2
|
||||
- litellm_security_tests
|
||||
- installing_litellm_on_python
|
||||
- installing_litellm_on_python_3_13
|
||||
|
|
|
|||
19
.github/workflows/ghcr_deploy.yml
vendored
19
.github/workflows/ghcr_deploy.yml
vendored
|
|
@ -338,7 +338,9 @@ jobs:
|
|||
if [ -z "${CHART_LIST}" ]; then
|
||||
echo "current-version=0.1.0" | tee -a $GITHUB_OUTPUT
|
||||
else
|
||||
printf '%s' "${CHART_LIST}" | grep '^version:' | awk 'BEGIN{FS=":"}{print "current-version="$2}' | tr -d " " | tee -a $GITHUB_OUTPUT
|
||||
# Extract version and strip any prerelease suffix (e.g., 0.1.827-latest -> 0.1.827)
|
||||
VERSION=$(printf '%s' "${CHART_LIST}" | grep '^version:' | awk 'BEGIN{FS=":"}{print $2}' | tr -d " " | cut -d'-' -f1)
|
||||
echo "current-version=${VERSION}" | tee -a $GITHUB_OUTPUT
|
||||
fi
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
|
@ -351,11 +353,24 @@ jobs:
|
|||
current-version: ${{ steps.current_version.outputs.current-version || '0.1.0' }}
|
||||
version-fragment: 'bug'
|
||||
|
||||
# Add suffix for non-stable releases (semantic versioning)
|
||||
- name: Calculate chart version with prerelease suffix
|
||||
id: chart_version
|
||||
shell: bash
|
||||
run: |
|
||||
BASE_VERSION="${{ steps.bump_version.outputs.next-version || '0.1.0' }}"
|
||||
RELEASE_TYPE="${{ github.event.inputs.release_type }}"
|
||||
if [ "$RELEASE_TYPE" = "stable" ]; then
|
||||
echo "version=${BASE_VERSION}" | tee -a $GITHUB_OUTPUT
|
||||
else
|
||||
echo "version=${BASE_VERSION}-${RELEASE_TYPE}" | tee -a $GITHUB_OUTPUT
|
||||
fi
|
||||
|
||||
- uses: ./.github/actions/helm-oci-chart-releaser
|
||||
with:
|
||||
name: ${{ env.CHART_NAME }}
|
||||
repository: ${{ env.REPO_OWNER }}
|
||||
tag: ${{ github.event.inputs.chartVersion || steps.bump_version.outputs.next-version || '0.1.0' }}
|
||||
tag: ${{ github.event.inputs.chartVersion || steps.chart_version.outputs.version || '0.1.0' }}
|
||||
app_version: ${{ steps.current_app_tag.outputs.latest_tag }}
|
||||
path: deploy/charts/${{ env.CHART_NAME }}
|
||||
registry: ${{ env.REGISTRY }}
|
||||
|
|
|
|||
1
.github/workflows/test-linting.yml
vendored
1
.github/workflows/test-linting.yml
vendored
|
|
@ -30,6 +30,7 @@ jobs:
|
|||
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
poetry lock
|
||||
poetry install --with dev
|
||||
poetry run pip install openai==1.100.1
|
||||
|
||||
|
|
|
|||
3
.github/workflows/test-litellm.yml
vendored
3
.github/workflows/test-litellm.yml
vendored
|
|
@ -27,6 +27,7 @@ jobs:
|
|||
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
poetry lock
|
||||
poetry install --with dev,proxy-dev --extras "proxy semantic-router"
|
||||
poetry run pip install "pytest-retry==1.6.3"
|
||||
poetry run pip install pytest-xdist
|
||||
|
|
@ -37,7 +38,7 @@ jobs:
|
|||
- name: Setup litellm-enterprise as local package
|
||||
run: |
|
||||
cd enterprise
|
||||
python -m pip install -e .
|
||||
poetry run pip install -e .
|
||||
cd ..
|
||||
- name: Run tests
|
||||
run: |
|
||||
|
|
|
|||
1
.github/workflows/test-mcp.yml
vendored
1
.github/workflows/test-mcp.yml
vendored
|
|
@ -27,6 +27,7 @@ jobs:
|
|||
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
poetry lock
|
||||
poetry install --with dev,proxy-dev --extras "proxy semantic-router"
|
||||
poetry run pip install "pytest==7.3.1"
|
||||
poetry run pip install "pytest-retry==1.6.3"
|
||||
|
|
|
|||
23
AGENTS.md
23
AGENTS.md
|
|
@ -94,6 +94,29 @@ LiteLLM supports MCP for agent workflows:
|
|||
- Support for external MCP servers (Zapier, Jira, Linear, etc.)
|
||||
- See `litellm/experimental_mcp_client/` and `litellm/proxy/_experimental/mcp_server/`
|
||||
|
||||
## RUNNING SCRIPTS
|
||||
|
||||
Use `poetry run python script.py` to run Python scripts in the project environment (for non-test files).
|
||||
|
||||
## GITHUB TEMPLATES
|
||||
|
||||
When opening issues or pull requests, follow these templates:
|
||||
|
||||
### Bug Reports (`.github/ISSUE_TEMPLATE/bug_report.yml`)
|
||||
- Describe what happened vs. expected behavior
|
||||
- Include relevant log output
|
||||
- Specify LiteLLM version
|
||||
- Indicate if you're part of an ML Ops team (helps with prioritization)
|
||||
|
||||
### Feature Requests (`.github/ISSUE_TEMPLATE/feature_request.yml`)
|
||||
- Clearly describe the feature
|
||||
- Explain motivation and use case with concrete examples
|
||||
|
||||
### Pull Requests (`.github/pull_request_template.md`)
|
||||
- Add at least 1 test in `tests/litellm/`
|
||||
- Ensure `make test-unit` passes
|
||||
|
||||
|
||||
## TESTING CONSIDERATIONS
|
||||
|
||||
1. **Provider Tests**: Test against real provider APIs when possible
|
||||
|
|
|
|||
19
CLAUDE.md
19
CLAUDE.md
|
|
@ -25,6 +25,25 @@ This file provides guidance to Claude Code (claude.ai/code) when working with co
|
|||
- `poetry run pytest tests/path/to/test_file.py -v` - Run specific test file
|
||||
- `poetry run pytest tests/path/to/test_file.py::test_function -v` - Run specific test
|
||||
|
||||
### Running Scripts
|
||||
- `poetry run python script.py` - Run Python scripts (use for non-test files)
|
||||
|
||||
### GitHub Issue & PR Templates
|
||||
When contributing to the project, use the appropriate templates:
|
||||
|
||||
**Bug Reports** (`.github/ISSUE_TEMPLATE/bug_report.yml`):
|
||||
- Describe what happened vs. what you expected
|
||||
- Include relevant log output
|
||||
- Specify your LiteLLM version
|
||||
|
||||
**Feature Requests** (`.github/ISSUE_TEMPLATE/feature_request.yml`):
|
||||
- Describe the feature clearly
|
||||
- Explain the motivation and use case
|
||||
|
||||
**Pull Requests** (`.github/pull_request_template.md`):
|
||||
- Add at least 1 test in `tests/litellm/`
|
||||
- Ensure `make test-unit` passes
|
||||
|
||||
## Architecture Overview
|
||||
|
||||
LiteLLM is a unified interface for 100+ LLM providers with two main components:
|
||||
|
|
|
|||
|
|
@ -24,8 +24,9 @@ Before contributing code to LiteLLM, you must sign our [Contributor License Agre
|
|||
### 1. Setup Your Local Development Environment
|
||||
|
||||
```bash
|
||||
# Clone the repository
|
||||
git clone https://github.com/BerriAI/litellm.git
|
||||
# Fork the repository on GitHub (click the Fork button at https://github.com/BerriAI/litellm)
|
||||
# Then clone your fork locally
|
||||
git clone https://github.com/YOUR_USERNAME/litellm.git
|
||||
cd litellm
|
||||
|
||||
# Create a new branch for your feature
|
||||
|
|
|
|||
15
Dockerfile
15
Dockerfile
|
|
@ -1,8 +1,8 @@
|
|||
# Base image for building
|
||||
ARG LITELLM_BUILD_IMAGE=cgr.dev/chainguard/python:latest-dev
|
||||
ARG LITELLM_BUILD_IMAGE=cgr.dev/chainguard/wolfi-base
|
||||
|
||||
# Runtime image
|
||||
ARG LITELLM_RUNTIME_IMAGE=cgr.dev/chainguard/python:latest-dev
|
||||
ARG LITELLM_RUNTIME_IMAGE=cgr.dev/chainguard/wolfi-base
|
||||
# Builder stage
|
||||
FROM $LITELLM_BUILD_IMAGE AS builder
|
||||
|
||||
|
|
@ -12,11 +12,9 @@ WORKDIR /app
|
|||
USER root
|
||||
|
||||
# Install build dependencies
|
||||
RUN apk add --no-cache gcc python3-dev openssl openssl-dev
|
||||
RUN apk add --no-cache bash gcc py3-pip python3 python3-dev openssl openssl-dev
|
||||
|
||||
|
||||
RUN pip install --upgrade pip>=24.3.1 && \
|
||||
pip install build
|
||||
RUN python -m pip install build
|
||||
|
||||
# Copy the current directory contents into the container at /app
|
||||
COPY . .
|
||||
|
|
@ -48,10 +46,7 @@ FROM $LITELLM_RUNTIME_IMAGE AS runtime
|
|||
USER root
|
||||
|
||||
# Install runtime dependencies
|
||||
RUN apk add --no-cache openssl tzdata
|
||||
|
||||
# Upgrade pip to fix CVE-2025-8869
|
||||
RUN pip install --upgrade pip>=24.3.1
|
||||
RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip
|
||||
|
||||
WORKDIR /app
|
||||
# Copy the current directory contents into the container at /app
|
||||
|
|
|
|||
19
GEMINI.md
19
GEMINI.md
|
|
@ -25,6 +25,25 @@ This file provides guidance to Gemini when working with code in this repository.
|
|||
- `poetry run pytest tests/path/to/test_file.py -v` - Run specific test file
|
||||
- `poetry run pytest tests/path/to/test_file.py::test_function -v` - Run specific test
|
||||
|
||||
### Running Scripts
|
||||
- `poetry run python script.py` - Run Python scripts (use for non-test files)
|
||||
|
||||
### GitHub Issue & PR Templates
|
||||
When contributing to the project, use the appropriate templates:
|
||||
|
||||
**Bug Reports** (`.github/ISSUE_TEMPLATE/bug_report.yml`):
|
||||
- Describe what happened vs. what you expected
|
||||
- Include relevant log output
|
||||
- Specify your LiteLLM version
|
||||
|
||||
**Feature Requests** (`.github/ISSUE_TEMPLATE/feature_request.yml`):
|
||||
- Describe the feature clearly
|
||||
- Explain the motivation and use case
|
||||
|
||||
**Pull Requests** (`.github/pull_request_template.md`):
|
||||
- Add at least 1 test in `tests/litellm/`
|
||||
- Ensure `make test-unit` passes
|
||||
|
||||
## Architecture Overview
|
||||
|
||||
LiteLLM is a unified interface for 100+ LLM providers with two main components:
|
||||
|
|
|
|||
6
Makefile
6
Makefile
|
|
@ -34,13 +34,13 @@ install-proxy-dev:
|
|||
|
||||
# CI-compatible installations (matches GitHub workflows exactly)
|
||||
install-dev-ci:
|
||||
pip install openai==1.99.5
|
||||
pip install openai==2.8.0
|
||||
poetry install --with dev
|
||||
pip install openai==1.99.5
|
||||
pip install openai==2.8.0
|
||||
|
||||
install-proxy-dev-ci:
|
||||
poetry install --with dev,proxy-dev --extras proxy
|
||||
pip install openai==1.99.5
|
||||
pip install openai==2.8.0
|
||||
|
||||
install-test-deps: install-proxy-dev
|
||||
poetry run pip install "pytest-retry==1.6.3"
|
||||
|
|
|
|||
16
README.md
16
README.md
|
|
@ -11,7 +11,7 @@
|
|||
<p align="center">Call all LLM APIs using the OpenAI format [Bedrock, Huggingface, VertexAI, TogetherAI, Azure, OpenAI, Groq etc.]
|
||||
<br>
|
||||
</p>
|
||||
<h4 align="center"><a href="https://docs.litellm.ai/docs/simple_proxy" target="_blank">LiteLLM Proxy Server (LLM Gateway)</a> | <a href="https://docs.litellm.ai/docs/hosted" target="_blank"> Hosted Proxy (Preview)</a> | <a href="https://docs.litellm.ai/docs/enterprise"target="_blank">Enterprise Tier</a></h4>
|
||||
<h4 align="center"><a href="https://docs.litellm.ai/docs/simple_proxy" target="_blank">LiteLLM Proxy Server (LLM Gateway)</a> | <a href="https://docs.litellm.ai/docs/enterprise#hosted-litellm-proxy" target="_blank"> Hosted Proxy</a> | <a href="https://docs.litellm.ai/docs/enterprise"target="_blank">Enterprise Tier</a></h4>
|
||||
<h4 align="center">
|
||||
<a href="https://pypi.org/project/litellm/" target="_blank">
|
||||
<img src="https://img.shields.io/pypi/v/litellm.svg" alt="PyPI Version">
|
||||
|
|
@ -40,7 +40,7 @@ LiteLLM manages:
|
|||
LiteLLM Performance: **8ms P95 latency** at 1k RPS (See benchmarks [here](https://docs.litellm.ai/docs/benchmarks))
|
||||
|
||||
[**Jump to LiteLLM Proxy (LLM Gateway) Docs**](https://github.com/BerriAI/litellm?tab=readme-ov-file#litellm-proxy-server-llm-gateway---docs) <br>
|
||||
[**Jump to Supported LLM Providers**](https://github.com/BerriAI/litellm?tab=readme-ov-file#supported-providers-docs)
|
||||
[**Jump to Supported LLM Providers**](https://docs.litellm.ai/docs/providers)
|
||||
|
||||
🚨 **Stable Release:** Use docker images with the `-stable` tag. These have undergone 12 hour load tests, before being published. [More information about the release cycle here](https://docs.litellm.ai/docs/proxy/release_cycle)
|
||||
|
||||
|
|
@ -48,10 +48,6 @@ Support for more providers. Missing a provider or LLM Platform, raise a [feature
|
|||
|
||||
# Usage ([**Docs**](https://docs.litellm.ai/docs/))
|
||||
|
||||
> [!IMPORTANT]
|
||||
> LiteLLM v1.0.0 now requires `openai>=1.0.0`. Migration guide [here](https://docs.litellm.ai/docs/migration)
|
||||
> LiteLLM v1.40.14+ now requires `pydantic>=2.0.0`. No changes required.
|
||||
|
||||
<a target="_blank" href="https://colab.research.google.com/github/BerriAI/litellm/blob/main/cookbook/liteLLM_Getting_Started.ipynb">
|
||||
<img src="https://colab.research.google.com/assets/colab-badge.svg" alt="Open In Colab"/>
|
||||
</a>
|
||||
|
|
@ -114,6 +110,8 @@ print(response)
|
|||
}
|
||||
```
|
||||
|
||||
> **Note:** LiteLLM also supports the [Responses API](https://docs.litellm.ai/docs/response_api) (`litellm.responses()`)
|
||||
|
||||
Call any model supported by a provider, with `model=<provider_name>/<model_name>`. There might be provider-specific details here, so refer to [provider docs for more information](https://docs.litellm.ai/docs/providers)
|
||||
|
||||
## Async ([Docs](https://docs.litellm.ai/docs/completion/stream#async-completion))
|
||||
|
|
@ -210,7 +208,7 @@ response = completion(model="openai/gpt-4o", messages=[{"role": "user", "content
|
|||
|
||||
Track spend + Load Balance across multiple projects
|
||||
|
||||
[Hosted Proxy (Preview)](https://docs.litellm.ai/docs/hosted)
|
||||
[Hosted Proxy](https://docs.litellm.ai/docs/enterprise#hosted-litellm-proxy)
|
||||
|
||||
The proxy provides:
|
||||
|
||||
|
|
@ -276,8 +274,6 @@ echo 'LITELLM_MASTER_KEY="sk-1234"' > .env
|
|||
# password generator to get a random hash for litellm salt key
|
||||
echo 'LITELLM_SALT_KEY="sk-1234"' >> .env
|
||||
|
||||
source .env
|
||||
|
||||
# Start
|
||||
docker compose up
|
||||
```
|
||||
|
|
@ -350,7 +346,7 @@ curl 'http://0.0.0.0:4000/key/generate' \
|
|||
| [Fireworks AI (`fireworks_ai`)](https://docs.litellm.ai/docs/providers/fireworks_ai) | ✅ | ✅ | ✅ | | | | | | | |
|
||||
| [FriendliAI (`friendliai`)](https://docs.litellm.ai/docs/providers/friendliai) | ✅ | ✅ | ✅ | | | | | | | |
|
||||
| [Galadriel (`galadriel`)](https://docs.litellm.ai/docs/providers/galadriel) | ✅ | ✅ | ✅ | | | | | | | |
|
||||
| [GitHub Copilot (`github_copilot`)](https://docs.litellm.ai/docs/providers/github_copilot) | ✅ | ✅ | ✅ | | | | | | | |
|
||||
| [GitHub Copilot (`github_copilot`)](https://docs.litellm.ai/docs/providers/github_copilot) | ✅ | ✅ | ✅ | ✅ | | | | | | |
|
||||
| [GitHub Models (`github`)](https://docs.litellm.ai/docs/providers/github) | ✅ | ✅ | ✅ | | | | | | | |
|
||||
| [Google - PaLM](https://docs.litellm.ai/docs/providers/palm) | ✅ | ✅ | ✅ | | | | | | | |
|
||||
| [Google - Vertex AI (`vertex_ai`)](https://docs.litellm.ai/docs/providers/vertex) | ✅ | ✅ | ✅ | ✅ | ✅ | | | | | |
|
||||
|
|
|
|||
|
|
@ -1,261 +0,0 @@
|
|||
# Vertex AI Environment Variables Setup Guide
|
||||
|
||||
## Overview
|
||||
|
||||
LiteLLM can load Vertex AI credentials from environment variables instead of storing them in config files. This is more secure and easier to manage for local development.
|
||||
|
||||
## Environment Variables
|
||||
|
||||
LiteLLM looks for these environment variables (in order of precedence):
|
||||
|
||||
### 1. **DEFAULT_VERTEXAI_PROJECT** (Required)
|
||||
Your GCP project ID that has Vertex AI enabled.
|
||||
|
||||
```bash
|
||||
export DEFAULT_VERTEXAI_PROJECT="my-gcp-project-id"
|
||||
```
|
||||
|
||||
### 2. **DEFAULT_VERTEXAI_LOCATION** (Required)
|
||||
The region/location for Vertex AI services.
|
||||
|
||||
```bash
|
||||
export DEFAULT_VERTEXAI_LOCATION="global"
|
||||
# or
|
||||
export DEFAULT_VERTEXAI_LOCATION="us-central1"
|
||||
```
|
||||
|
||||
Common locations:
|
||||
- `global` - For Discovery Engine and global services
|
||||
- `us-central1` - US Central region
|
||||
- `us-east1` - US East region
|
||||
- `europe-west1` - Europe West region
|
||||
- `asia-southeast1` - Asia Southeast region
|
||||
|
||||
### 3. **DEFAULT_GOOGLE_APPLICATION_CREDENTIALS** (Required)
|
||||
Path to your service account JSON key file.
|
||||
|
||||
```bash
|
||||
export DEFAULT_GOOGLE_APPLICATION_CREDENTIALS="/path/to/service-account-key.json"
|
||||
```
|
||||
|
||||
### 4. **GOOGLE_APPLICATION_CREDENTIALS** (Fallback)
|
||||
Standard Google Cloud environment variable (used as fallback).
|
||||
|
||||
```bash
|
||||
export GOOGLE_APPLICATION_CREDENTIALS="/path/to/service-account-key.json"
|
||||
```
|
||||
|
||||
## Quick Setup
|
||||
|
||||
### Option 1: Interactive Script
|
||||
|
||||
```bash
|
||||
chmod +x setup_vertex_env.sh
|
||||
source setup_vertex_env.sh
|
||||
```
|
||||
|
||||
### Option 2: Manual Setup
|
||||
|
||||
1. **Set environment variables** (for current session):
|
||||
|
||||
```bash
|
||||
export DEFAULT_VERTEXAI_PROJECT="your-project-id"
|
||||
export DEFAULT_VERTEXAI_LOCATION="global"
|
||||
export DEFAULT_GOOGLE_APPLICATION_CREDENTIALS="$HOME/.gcp/service-account.json"
|
||||
export GOOGLE_APPLICATION_CREDENTIALS="$HOME/.gcp/service-account.json"
|
||||
```
|
||||
|
||||
2. **Make them persistent** (add to `~/.zshrc` or `~/.bashrc`):
|
||||
|
||||
```bash
|
||||
echo 'export DEFAULT_VERTEXAI_PROJECT="your-project-id"' >> ~/.zshrc
|
||||
echo 'export DEFAULT_VERTEXAI_LOCATION="global"' >> ~/.zshrc
|
||||
echo 'export DEFAULT_GOOGLE_APPLICATION_CREDENTIALS="$HOME/.gcp/service-account.json"' >> ~/.zshrc
|
||||
echo 'export GOOGLE_APPLICATION_CREDENTIALS="$HOME/.gcp/service-account.json"' >> ~/.zshrc
|
||||
```
|
||||
|
||||
3. **Reload your shell**:
|
||||
|
||||
```bash
|
||||
source ~/.zshrc
|
||||
```
|
||||
|
||||
## Service Account Setup
|
||||
|
||||
### 1. Create a Service Account
|
||||
|
||||
```bash
|
||||
gcloud iam service-accounts create litellm-vertex-sa \
|
||||
--display-name="LiteLLM Vertex AI Service Account"
|
||||
```
|
||||
|
||||
### 2. Grant Necessary Permissions
|
||||
|
||||
For Discovery Engine (vector stores):
|
||||
```bash
|
||||
gcloud projects add-iam-policy-binding YOUR_PROJECT_ID \
|
||||
--member="serviceAccount:litellm-vertex-sa@YOUR_PROJECT_ID.iam.gserviceaccount.com" \
|
||||
--role="roles/discoveryengine.viewer"
|
||||
|
||||
gcloud projects add-iam-policy-binding YOUR_PROJECT_ID \
|
||||
--member="serviceAccount:litellm-vertex-sa@YOUR_PROJECT_ID.iam.gserviceaccount.com" \
|
||||
--role="roles/discoveryengine.dataStoreEditor"
|
||||
```
|
||||
|
||||
For general Vertex AI:
|
||||
```bash
|
||||
gcloud projects add-iam-policy-binding YOUR_PROJECT_ID \
|
||||
--member="serviceAccount:litellm-vertex-sa@YOUR_PROJECT_ID.iam.gserviceaccount.com" \
|
||||
--role="roles/aiplatform.user"
|
||||
```
|
||||
|
||||
### 3. Create and Download Key
|
||||
|
||||
```bash
|
||||
gcloud iam service-accounts keys create ~/service-account-key.json \
|
||||
--iam-account=litellm-vertex-sa@YOUR_PROJECT_ID.iam.gserviceaccount.com
|
||||
```
|
||||
|
||||
## Verify Setup
|
||||
|
||||
### Check Environment Variables
|
||||
|
||||
```bash
|
||||
python3 << 'EOF'
|
||||
import os
|
||||
print("✓ Environment Variables:")
|
||||
print(f" DEFAULT_VERTEXAI_PROJECT: {os.getenv('DEFAULT_VERTEXAI_PROJECT')}")
|
||||
print(f" DEFAULT_VERTEXAI_LOCATION: {os.getenv('DEFAULT_VERTEXAI_LOCATION')}")
|
||||
print(f" DEFAULT_GOOGLE_APPLICATION_CREDENTIALS: {os.getenv('DEFAULT_GOOGLE_APPLICATION_CREDENTIALS')}")
|
||||
print(f" GOOGLE_APPLICATION_CREDENTIALS: {os.getenv('GOOGLE_APPLICATION_CREDENTIALS')}")
|
||||
|
||||
# Check if credentials file exists
|
||||
creds_path = os.getenv('DEFAULT_GOOGLE_APPLICATION_CREDENTIALS')
|
||||
if creds_path and os.path.exists(creds_path):
|
||||
print(f"\n✅ Credentials file found at: {creds_path}")
|
||||
else:
|
||||
print(f"\n❌ Credentials file NOT found at: {creds_path}")
|
||||
EOF
|
||||
```
|
||||
|
||||
### Test Authentication
|
||||
|
||||
```bash
|
||||
python3 << 'EOF'
|
||||
import os
|
||||
import json
|
||||
from google.oauth2 import service_account
|
||||
from google.auth.transport.requests import Request
|
||||
|
||||
creds_path = os.getenv('DEFAULT_GOOGLE_APPLICATION_CREDENTIALS')
|
||||
project = os.getenv('DEFAULT_VERTEXAI_PROJECT')
|
||||
|
||||
try:
|
||||
# Load credentials
|
||||
credentials = service_account.Credentials.from_service_account_file(
|
||||
creds_path,
|
||||
scopes=['https://www.googleapis.com/auth/cloud-platform']
|
||||
)
|
||||
|
||||
# Get access token
|
||||
credentials.refresh(Request())
|
||||
|
||||
print("✅ Authentication successful!")
|
||||
print(f" Project: {project}")
|
||||
print(f" Service Account: {credentials.service_account_email}")
|
||||
print(f" Token expiry: {credentials.expiry}")
|
||||
|
||||
except Exception as e:
|
||||
print(f"❌ Authentication failed: {e}")
|
||||
EOF
|
||||
```
|
||||
|
||||
## Using with Vector Store Passthrough
|
||||
|
||||
Once your environment is set up, the vector store passthrough will work in two ways:
|
||||
|
||||
### 1. **With Vector Store Config** (Priority 1)
|
||||
If you have a vector store configured with its own credentials in `litellm_params`, those will be used first:
|
||||
|
||||
```yaml
|
||||
vector_stores:
|
||||
- vector_store_id: test-store-123
|
||||
custom_llm_provider: vertex_ai
|
||||
litellm_params:
|
||||
vertex_project: "specific-project"
|
||||
vertex_location: "us-central1"
|
||||
vertex_credentials: "{...}" # Inline credentials
|
||||
```
|
||||
|
||||
### 2. **Environment Variables Fallback** (Priority 2)
|
||||
If the vector store doesn't have explicit credentials, it falls back to your environment variables:
|
||||
|
||||
```yaml
|
||||
vector_stores:
|
||||
- vector_store_id: test-store-123
|
||||
custom_llm_provider: vertex_ai
|
||||
# No litellm_params - will use DEFAULT_VERTEXAI_PROJECT, DEFAULT_VERTEXAI_LOCATION, etc.
|
||||
```
|
||||
|
||||
### 3. **Model Config Fallback** (Priority 3)
|
||||
If neither above work, it looks for credentials in your model configuration.
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
### "No credentials found"
|
||||
|
||||
Check that all environment variables are set:
|
||||
```bash
|
||||
env | grep -E "(DEFAULT_VERTEXAI|GOOGLE_APPLICATION_CREDENTIALS)"
|
||||
```
|
||||
|
||||
### "Authentication failed"
|
||||
|
||||
Verify your service account key is valid:
|
||||
```bash
|
||||
cat $DEFAULT_GOOGLE_APPLICATION_CREDENTIALS | python3 -m json.tool
|
||||
```
|
||||
|
||||
### "Permission denied"
|
||||
|
||||
Ensure your service account has the necessary roles:
|
||||
```bash
|
||||
gcloud projects get-iam-policy YOUR_PROJECT_ID \
|
||||
--flatten="bindings[].members" \
|
||||
--filter="bindings.members:serviceAccount:litellm-vertex-sa@*"
|
||||
```
|
||||
|
||||
### Different Credentials for Different Projects
|
||||
|
||||
If you need to use different credentials for different vector stores, configure them explicitly in the vector store config rather than relying on environment variables.
|
||||
|
||||
## Start LiteLLM Proxy
|
||||
|
||||
Once your environment is configured:
|
||||
|
||||
```bash
|
||||
# Start the proxy (it will automatically load env vars)
|
||||
litellm --config proxy_server_config.yaml
|
||||
|
||||
# Or with debug logging
|
||||
export LITELLM_LOG=DEBUG
|
||||
litellm --config proxy_server_config.yaml
|
||||
```
|
||||
|
||||
You should see logs like:
|
||||
```
|
||||
Vertex: Loading vertex credentials from /path/to/service-account.json
|
||||
Found credentials for vertex_ai_default
|
||||
```
|
||||
|
||||
## Test the Endpoint
|
||||
|
||||
```bash
|
||||
curl -X POST http://0.0.0.0:4000/vertex_ai/discovery/v1/projects/fake-project/locations/global/dataStores/test-store-123/servingConfigs/default_config:search \
|
||||
-H 'Authorization: Bearer YOUR_LITELLM_API_KEY' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-d '{"query": "test query"}'
|
||||
```
|
||||
|
||||
The proxy will use your environment credentials to make the request to Vertex AI!
|
||||
|
||||
|
|
@ -69,10 +69,15 @@ run_grype_scans() {
|
|||
# Allowlist of CVEs to be ignored in failure threshold/reporting
|
||||
# - CVE-2025-8869: Not applicable on Python >=3.13 (PEP 706 implemented); pip fallback unused; no OS-level fix
|
||||
# - GHSA-4xh5-x5gv-qwph: GitHub Security Advisory alias for CVE-2025-8869
|
||||
# - GHSA-5j98-mcp5-4vw2: glob CLI command injection via -c/--cmd; glob CLI is not used in the litellm runtime image,
|
||||
# and the vulnerable versions are pulled in only via OS-level/node tooling outside of our application code
|
||||
ALLOWED_CVES=(
|
||||
"CVE-2025-8869"
|
||||
"GHSA-4xh5-x5gv-qwph"
|
||||
"CVE-2025-8291" # no fix available as of Oct 11, 2025
|
||||
"GHSA-5j98-mcp5-4vw2"
|
||||
"CVE-2025-13836" # Python 3.13 HTTP response reading OOM/DoS - no fix available in base image
|
||||
"CVE-2025-12084" # Python 3.13 xml.dom.minidom quadratic algorithm - no fix available in base image
|
||||
)
|
||||
|
||||
# Build JSON array of allowlisted CVE IDs for jq
|
||||
|
|
|
|||
12
cookbook/LiteLLM_CometAPI.ipynb
vendored
12
cookbook/LiteLLM_CometAPI.ipynb
vendored
|
|
@ -28,7 +28,7 @@
|
|||
"Requirement already satisfied: importlib-metadata>=6.8.0 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from litellm) (8.6.1)\n",
|
||||
"Requirement already satisfied: jinja2<4.0.0,>=3.1.2 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from litellm) (3.1.6)\n",
|
||||
"Requirement already satisfied: jsonschema<5.0.0,>=4.22.0 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from litellm) (4.25.1)\n",
|
||||
"Requirement already satisfied: openai>=1.99.5 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from litellm) (1.109.1)\n",
|
||||
"Requirement already satisfied: openai>=2.8.0 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from litellm) (1.109.1)\n",
|
||||
"Requirement already satisfied: pydantic<3.0.0,>=2.5.0 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from litellm) (2.11.10)\n",
|
||||
"Requirement already satisfied: python-dotenv>=0.2.0 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from litellm) (1.1.1)\n",
|
||||
"Requirement already satisfied: tiktoken>=0.7.0 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from litellm) (0.12.0)\n",
|
||||
|
|
@ -50,11 +50,11 @@
|
|||
"Requirement already satisfied: jsonschema-specifications>=2023.03.6 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from jsonschema<5.0.0,>=4.22.0->litellm) (2025.9.1)\n",
|
||||
"Requirement already satisfied: referencing>=0.28.4 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from jsonschema<5.0.0,>=4.22.0->litellm) (0.36.2)\n",
|
||||
"Requirement already satisfied: rpds-py>=0.7.1 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from jsonschema<5.0.0,>=4.22.0->litellm) (0.27.1)\n",
|
||||
"Requirement already satisfied: distro<2,>=1.7.0 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from openai>=1.99.5->litellm) (1.9.0)\n",
|
||||
"Requirement already satisfied: jiter<1,>=0.4.0 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from openai>=1.99.5->litellm) (0.11.0)\n",
|
||||
"Requirement already satisfied: sniffio in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from openai>=1.99.5->litellm) (1.3.1)\n",
|
||||
"Requirement already satisfied: tqdm>4 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from openai>=1.99.5->litellm) (4.67.1)\n",
|
||||
"Requirement already satisfied: typing-extensions<5,>=4.11 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from openai>=1.99.5->litellm) (4.15.0)\n",
|
||||
"Requirement already satisfied: distro<2,>=1.7.0 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from openai>=2.8.0->litellm) (1.9.0)\n",
|
||||
"Requirement already satisfied: jiter<1,>=0.4.0 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from openai>=2.8.0->litellm) (0.11.0)\n",
|
||||
"Requirement already satisfied: sniffio in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from openai>=2.8.0->litellm) (1.3.1)\n",
|
||||
"Requirement already satisfied: tqdm>4 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from openai>=2.8.0->litellm) (4.67.1)\n",
|
||||
"Requirement already satisfied: typing-extensions<5,>=4.11 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from openai>=2.8.0->litellm) (4.15.0)\n",
|
||||
"Requirement already satisfied: annotated-types>=0.6.0 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from pydantic<3.0.0,>=2.5.0->litellm) (0.7.0)\n",
|
||||
"Requirement already satisfied: pydantic-core==2.33.2 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from pydantic<3.0.0,>=2.5.0->litellm) (2.33.2)\n",
|
||||
"Requirement already satisfied: typing-inspection>=0.4.0 in /Users/xmx/.miniforge3/lib/python3.12/site-packages (from pydantic<3.0.0,>=2.5.0->litellm) (0.4.2)\n",
|
||||
|
|
|
|||
2
cookbook/LiteLLM_HuggingFace.ipynb
vendored
2
cookbook/LiteLLM_HuggingFace.ipynb
vendored
|
|
@ -131,7 +131,7 @@
|
|||
" {\n",
|
||||
" \"type\": \"image_url\",\n",
|
||||
" \"image_url\": {\n",
|
||||
" \"url\": \"https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg\",\n",
|
||||
" \"url\": \"https://awsmp-logos.s3.amazonaws.com/seller-xw5kijmvmzasy/c233c9ade2ccb5491072ae232c814942.png\",\n",
|
||||
" },\n",
|
||||
" },\n",
|
||||
" ],\n",
|
||||
|
|
|
|||
|
|
@ -0,0 +1,279 @@
|
|||
# Braintrust Prompt Wrapper for LiteLLM
|
||||
|
||||
This directory contains a wrapper server that enables LiteLLM to use prompts from [Braintrust](https://www.braintrust.dev/) through the generic prompt management API.
|
||||
|
||||
## Architecture
|
||||
|
||||
```
|
||||
┌─────────────┐ ┌──────────────────────┐ ┌─────────────┐
|
||||
│ LiteLLM │ ──────> │ Wrapper Server │ ──────> │ Braintrust │
|
||||
│ Client │ │ (This Server) │ │ API │
|
||||
└─────────────┘ └──────────────────────┘ └─────────────┘
|
||||
Uses generic Transforms Stores actual
|
||||
prompt manager Braintrust format prompt templates
|
||||
to LiteLLM format
|
||||
```
|
||||
|
||||
## Components
|
||||
|
||||
### 1. Generic Prompt Manager (`litellm/integrations/generic_prompt_management/`)
|
||||
|
||||
A generic client that can work with any API implementing the `/beta/litellm_prompt_management` endpoint.
|
||||
|
||||
**Expected API Response Format:**
|
||||
```json
|
||||
{
|
||||
"prompt_id": "string",
|
||||
"prompt_template": [
|
||||
{"role": "system", "content": "You are a helpful assistant"},
|
||||
{"role": "user", "content": "Hello {name}"}
|
||||
],
|
||||
"prompt_template_model": "gpt-4",
|
||||
"prompt_template_optional_params": {
|
||||
"temperature": 0.7,
|
||||
"max_tokens": 100
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### 2. Braintrust Wrapper Server (`braintrust_prompt_wrapper_server.py`)
|
||||
|
||||
A FastAPI server that:
|
||||
- Implements the `/beta/litellm_prompt_management` endpoint
|
||||
- Fetches prompts from Braintrust API
|
||||
- Transforms Braintrust response format to LiteLLM format
|
||||
|
||||
## Setup
|
||||
|
||||
### Install Dependencies
|
||||
|
||||
```bash
|
||||
pip install fastapi uvicorn httpx litellm
|
||||
```
|
||||
|
||||
### Set Environment Variables
|
||||
|
||||
```bash
|
||||
export BRAINTRUST_API_KEY="your-braintrust-api-key"
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Step 1: Start the Wrapper Server
|
||||
|
||||
```bash
|
||||
python braintrust_prompt_wrapper_server.py
|
||||
```
|
||||
|
||||
The server will start on `http://localhost:8080` by default.
|
||||
|
||||
You can customize the port and host:
|
||||
```bash
|
||||
export PORT=8000
|
||||
export HOST=0.0.0.0
|
||||
python braintrust_prompt_wrapper_server.py
|
||||
```
|
||||
|
||||
### Step 2: Use with LiteLLM
|
||||
|
||||
```python
|
||||
import litellm
|
||||
from litellm.integrations.generic_prompt_management import GenericPromptManager
|
||||
|
||||
# Configure the generic prompt manager to use your wrapper server
|
||||
generic_config = {
|
||||
"api_base": "http://localhost:8080",
|
||||
"api_key": "your-braintrust-api-key", # Will be passed to Braintrust
|
||||
"timeout": 30,
|
||||
}
|
||||
|
||||
# Create the prompt manager
|
||||
prompt_manager = GenericPromptManager(**generic_config)
|
||||
|
||||
# Use with completion
|
||||
response = litellm.completion(
|
||||
model="generic_prompt/gpt-4",
|
||||
prompt_id="your-braintrust-prompt-id",
|
||||
prompt_variables={"name": "World"}, # Variables to substitute
|
||||
messages=[{"role": "user", "content": "Additional message"}]
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
### Step 3: Direct API Testing
|
||||
|
||||
You can also test the wrapper API directly:
|
||||
|
||||
```bash
|
||||
# Test with curl
|
||||
curl -H "Authorization: Bearer YOUR_BRAINTRUST_TOKEN" \
|
||||
"http://localhost:8080/beta/litellm_prompt_management?prompt_id=YOUR_PROMPT_ID"
|
||||
|
||||
# Health check
|
||||
curl http://localhost:8080/health
|
||||
|
||||
# Service info
|
||||
curl http://localhost:8080/
|
||||
```
|
||||
|
||||
## API Documentation
|
||||
|
||||
Once the server is running, visit:
|
||||
- Swagger UI: `http://localhost:8080/docs`
|
||||
- ReDoc: `http://localhost:8080/redoc`
|
||||
|
||||
## Braintrust Format Transformation
|
||||
|
||||
The wrapper automatically transforms Braintrust's response format:
|
||||
|
||||
**Braintrust API Response:**
|
||||
```json
|
||||
{
|
||||
"id": "prompt-123",
|
||||
"prompt_data": {
|
||||
"prompt": {
|
||||
"type": "chat",
|
||||
"messages": [
|
||||
{
|
||||
"role": "system",
|
||||
"content": "You are a helpful assistant"
|
||||
}
|
||||
]
|
||||
},
|
||||
"options": {
|
||||
"model": "gpt-4",
|
||||
"params": {
|
||||
"temperature": 0.7,
|
||||
"max_tokens": 100
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Transformed to LiteLLM Format:**
|
||||
```json
|
||||
{
|
||||
"prompt_id": "prompt-123",
|
||||
"prompt_template": [
|
||||
{
|
||||
"role": "system",
|
||||
"content": "You are a helpful assistant"
|
||||
}
|
||||
],
|
||||
"prompt_template_model": "gpt-4",
|
||||
"prompt_template_optional_params": {
|
||||
"temperature": 0.7,
|
||||
"max_tokens": 100
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Supported Parameters
|
||||
|
||||
The wrapper automatically maps these Braintrust parameters to LiteLLM:
|
||||
|
||||
- `temperature`
|
||||
- `max_tokens` / `max_completion_tokens`
|
||||
- `top_p`
|
||||
- `frequency_penalty`
|
||||
- `presence_penalty`
|
||||
- `n`
|
||||
- `stop`
|
||||
- `response_format`
|
||||
- `tool_choice`
|
||||
- `function_call`
|
||||
- `tools`
|
||||
|
||||
## Variable Substitution
|
||||
|
||||
The generic prompt manager supports simple variable substitution:
|
||||
|
||||
```python
|
||||
# In your Braintrust prompt:
|
||||
# "Hello {name}, welcome to {place}!"
|
||||
|
||||
# In your code:
|
||||
prompt_variables = {
|
||||
"name": "Alice",
|
||||
"place": "Wonderland"
|
||||
}
|
||||
|
||||
# Result:
|
||||
# "Hello Alice, welcome to Wonderland!"
|
||||
```
|
||||
|
||||
Supports both `{variable}` and `{{variable}}` syntax.
|
||||
|
||||
## Error Handling
|
||||
|
||||
The wrapper provides detailed error messages:
|
||||
|
||||
- **401**: Missing or invalid Braintrust API token
|
||||
- **404**: Prompt not found in Braintrust
|
||||
- **502**: Failed to connect to Braintrust API
|
||||
- **500**: Error transforming response
|
||||
|
||||
## Production Deployment
|
||||
|
||||
For production use:
|
||||
|
||||
1. **Use HTTPS**: Deploy behind a reverse proxy with SSL
|
||||
2. **Authentication**: Add authentication to the wrapper endpoint if needed
|
||||
3. **Rate Limiting**: Implement rate limiting to prevent abuse
|
||||
4. **Caching**: Consider caching prompt responses
|
||||
5. **Monitoring**: Add logging and monitoring
|
||||
|
||||
Example with Docker:
|
||||
|
||||
```dockerfile
|
||||
FROM python:3.11-slim
|
||||
|
||||
WORKDIR /app
|
||||
|
||||
RUN pip install fastapi uvicorn httpx
|
||||
|
||||
COPY braintrust_prompt_wrapper_server.py .
|
||||
|
||||
ENV PORT=8080
|
||||
ENV HOST=0.0.0.0
|
||||
|
||||
EXPOSE 8080
|
||||
|
||||
CMD ["python", "braintrust_prompt_wrapper_server.py"]
|
||||
```
|
||||
|
||||
## Extending to Other Providers
|
||||
|
||||
This pattern can be used with any prompt management provider:
|
||||
|
||||
1. Create a wrapper server that implements `/beta/litellm_prompt_management`
|
||||
2. Transform the provider's response to LiteLLM format
|
||||
3. Use the generic prompt manager to connect
|
||||
|
||||
Example providers:
|
||||
- Langsmith
|
||||
- PromptLayer
|
||||
- Humanloop
|
||||
- Custom internal systems
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
### "No Braintrust API token provided"
|
||||
- Set `BRAINTRUST_API_KEY` environment variable
|
||||
- Or pass token in `Authorization: Bearer TOKEN` header
|
||||
|
||||
### "Failed to connect to Braintrust API"
|
||||
- Check your internet connection
|
||||
- Verify Braintrust API is accessible
|
||||
- Check firewall settings
|
||||
|
||||
### "Prompt not found"
|
||||
- Verify the prompt ID exists in Braintrust
|
||||
- Check that your API token has access to the prompt
|
||||
|
||||
## License
|
||||
|
||||
This wrapper is part of the LiteLLM project and follows the same license.
|
||||
|
||||
|
|
@ -0,0 +1,274 @@
|
|||
"""
|
||||
Mock server that implements the /beta/litellm_prompt_management endpoint
|
||||
and acts as a wrapper for calling the Braintrust API.
|
||||
|
||||
This server transforms Braintrust's prompt API response into the format
|
||||
expected by LiteLLM's generic prompt management client.
|
||||
|
||||
Usage:
|
||||
python braintrust_prompt_wrapper_server.py
|
||||
|
||||
# Then test with:
|
||||
curl -H "Authorization: Bearer YOUR_BRAINTRUST_TOKEN" \
|
||||
"http://localhost:8080/beta/litellm_prompt_management?prompt_id=YOUR_PROMPT_ID"
|
||||
"""
|
||||
|
||||
import json
|
||||
import os
|
||||
from typing import Any, Dict, List, Optional
|
||||
|
||||
import httpx
|
||||
from fastapi import FastAPI, HTTPException, Header, Query
|
||||
from fastapi.responses import JSONResponse
|
||||
import uvicorn
|
||||
|
||||
|
||||
app = FastAPI(
|
||||
title="Braintrust Prompt Wrapper",
|
||||
description="Wrapper server for Braintrust prompts to work with LiteLLM",
|
||||
version="1.0.0",
|
||||
)
|
||||
|
||||
|
||||
def transform_braintrust_message(message: Dict[str, Any]) -> Dict[str, str]:
|
||||
"""
|
||||
Transform a Braintrust message to LiteLLM format.
|
||||
|
||||
Braintrust message format:
|
||||
{
|
||||
"role": "system",
|
||||
"content": "...",
|
||||
"name": "..." (optional)
|
||||
}
|
||||
|
||||
LiteLLM format:
|
||||
{
|
||||
"role": "system",
|
||||
"content": "..."
|
||||
}
|
||||
"""
|
||||
result = {
|
||||
"role": message.get("role", "user"),
|
||||
"content": message.get("content", ""),
|
||||
}
|
||||
|
||||
# Include name if present
|
||||
if "name" in message:
|
||||
result["name"] = message["name"]
|
||||
|
||||
return result
|
||||
|
||||
|
||||
def transform_braintrust_response(
|
||||
braintrust_response: Dict[str, Any],
|
||||
) -> Dict[str, Any]:
|
||||
"""
|
||||
Transform Braintrust API response to LiteLLM prompt management format.
|
||||
|
||||
Braintrust response format:
|
||||
{
|
||||
"objects": [{
|
||||
"id": "prompt_id",
|
||||
"prompt_data": {
|
||||
"prompt": {
|
||||
"type": "chat",
|
||||
"messages": [...],
|
||||
"tools": "..."
|
||||
},
|
||||
"options": {
|
||||
"model": "gpt-4",
|
||||
"params": {
|
||||
"temperature": 0.7,
|
||||
"max_tokens": 100,
|
||||
...
|
||||
}
|
||||
}
|
||||
}
|
||||
}]
|
||||
}
|
||||
|
||||
LiteLLM format:
|
||||
{
|
||||
"prompt_id": "prompt_id",
|
||||
"prompt_template": [...],
|
||||
"prompt_template_model": "gpt-4",
|
||||
"prompt_template_optional_params": {...}
|
||||
}
|
||||
"""
|
||||
# Extract the first object from the objects array if it exists
|
||||
if "objects" in braintrust_response and len(braintrust_response["objects"]) > 0:
|
||||
prompt_object = braintrust_response["objects"][0]
|
||||
else:
|
||||
prompt_object = braintrust_response
|
||||
|
||||
prompt_data = prompt_object.get("prompt_data", {})
|
||||
prompt_info = prompt_data.get("prompt", {})
|
||||
options = prompt_data.get("options", {})
|
||||
|
||||
# Extract messages
|
||||
messages = prompt_info.get("messages", [])
|
||||
transformed_messages = [transform_braintrust_message(msg) for msg in messages]
|
||||
|
||||
# Extract model
|
||||
model = options.get("model")
|
||||
|
||||
# Extract optional parameters
|
||||
params = options.get("params", {})
|
||||
optional_params: Dict[str, Any] = {}
|
||||
|
||||
# Map common parameters
|
||||
param_mapping = {
|
||||
"temperature": "temperature",
|
||||
"max_tokens": "max_tokens",
|
||||
"max_completion_tokens": "max_tokens", # Alternative name
|
||||
"top_p": "top_p",
|
||||
"frequency_penalty": "frequency_penalty",
|
||||
"presence_penalty": "presence_penalty",
|
||||
"n": "n",
|
||||
"stop": "stop",
|
||||
}
|
||||
|
||||
for braintrust_param, litellm_param in param_mapping.items():
|
||||
if braintrust_param in params:
|
||||
value = params[braintrust_param]
|
||||
if value is not None:
|
||||
optional_params[litellm_param] = value
|
||||
|
||||
# Handle response_format
|
||||
if "response_format" in params:
|
||||
optional_params["response_format"] = params["response_format"]
|
||||
|
||||
# Handle tool_choice
|
||||
if "tool_choice" in params:
|
||||
optional_params["tool_choice"] = params["tool_choice"]
|
||||
|
||||
# Handle function_call
|
||||
if "function_call" in params:
|
||||
optional_params["function_call"] = params["function_call"]
|
||||
|
||||
# Add tools if present
|
||||
if "tools" in prompt_info and prompt_info["tools"]:
|
||||
optional_params["tools"] = prompt_info["tools"]
|
||||
|
||||
# Handle tool_functions from prompt_data
|
||||
if "tool_functions" in prompt_data and prompt_data["tool_functions"]:
|
||||
optional_params["tool_functions"] = prompt_data["tool_functions"]
|
||||
|
||||
return {
|
||||
"prompt_id": prompt_object.get("id"),
|
||||
"prompt_template": transformed_messages,
|
||||
"prompt_template_model": model,
|
||||
"prompt_template_optional_params": optional_params if optional_params else None,
|
||||
}
|
||||
|
||||
|
||||
@app.get("/beta/litellm_prompt_management")
|
||||
async def get_prompt(
|
||||
prompt_id: str = Query(..., description="The Braintrust prompt ID to fetch"),
|
||||
authorization: Optional[str] = Header(
|
||||
None, description="Bearer token for Braintrust API"
|
||||
),
|
||||
) -> JSONResponse:
|
||||
"""
|
||||
Fetch a prompt from Braintrust and transform it to LiteLLM format.
|
||||
|
||||
Args:
|
||||
prompt_id: The Braintrust prompt ID
|
||||
authorization: Bearer token for Braintrust API (from header)
|
||||
|
||||
Returns:
|
||||
JSONResponse with the transformed prompt data
|
||||
"""
|
||||
# Extract token from Authorization header or environment
|
||||
braintrust_token = None
|
||||
if authorization and authorization.startswith("Bearer "):
|
||||
braintrust_token = authorization.replace("Bearer ", "")
|
||||
else:
|
||||
braintrust_token = os.getenv("BRAINTRUST_API_KEY")
|
||||
|
||||
if not braintrust_token:
|
||||
raise HTTPException(
|
||||
status_code=401,
|
||||
detail="No Braintrust API token provided. Pass via Authorization header or set BRAINTRUST_API_KEY environment variable.",
|
||||
)
|
||||
|
||||
# Call Braintrust API
|
||||
braintrust_url = f"https://api.braintrust.dev/v1/prompt/{prompt_id}"
|
||||
headers = {
|
||||
"Authorization": f"Bearer {braintrust_token}",
|
||||
"Accept": "application/json",
|
||||
}
|
||||
print(f"headers: {headers}")
|
||||
print(f"braintrust_url: {braintrust_url}")
|
||||
print(f"braintrust_token: {braintrust_token}")
|
||||
|
||||
try:
|
||||
async with httpx.AsyncClient(timeout=30.0) as client:
|
||||
response = await client.get(braintrust_url, headers=headers)
|
||||
response.raise_for_status()
|
||||
braintrust_data = response.json()
|
||||
except httpx.HTTPStatusError as e:
|
||||
raise HTTPException(
|
||||
status_code=e.response.status_code,
|
||||
detail=f"Braintrust API error: {e.response.text}",
|
||||
)
|
||||
except httpx.RequestError as e:
|
||||
raise HTTPException(
|
||||
status_code=502,
|
||||
detail=f"Failed to connect to Braintrust API: {str(e)}",
|
||||
)
|
||||
except json.JSONDecodeError as e:
|
||||
raise HTTPException(
|
||||
status_code=502,
|
||||
detail=f"Failed to parse Braintrust API response: {str(e)}",
|
||||
)
|
||||
|
||||
print(f"braintrust_data: {braintrust_data}")
|
||||
# Transform the response
|
||||
try:
|
||||
transformed_data = transform_braintrust_response(braintrust_data)
|
||||
print(f"transformed_data: {transformed_data}")
|
||||
return JSONResponse(content=transformed_data)
|
||||
except Exception as e:
|
||||
raise HTTPException(
|
||||
status_code=500,
|
||||
detail=f"Failed to transform Braintrust response: {str(e)}",
|
||||
)
|
||||
|
||||
|
||||
@app.get("/health")
|
||||
async def health_check():
|
||||
"""Health check endpoint."""
|
||||
return {"status": "healthy", "service": "braintrust-prompt-wrapper"}
|
||||
|
||||
|
||||
@app.get("/")
|
||||
async def root():
|
||||
"""Root endpoint with service information."""
|
||||
return {
|
||||
"service": "Braintrust Prompt Wrapper for LiteLLM",
|
||||
"version": "1.0.0",
|
||||
"endpoints": {
|
||||
"prompt_management": "/beta/litellm_prompt_management?prompt_id=<id>",
|
||||
"health": "/health",
|
||||
},
|
||||
"documentation": "/docs",
|
||||
}
|
||||
|
||||
|
||||
def main():
|
||||
"""Run the server."""
|
||||
port = int(os.getenv("PORT", "8080"))
|
||||
host = os.getenv("HOST", "0.0.0.0")
|
||||
|
||||
print(f"🚀 Starting Braintrust Prompt Wrapper Server on {host}:{port}")
|
||||
print(f"📚 API Documentation available at http://{host}:{port}/docs")
|
||||
print(
|
||||
f"🔑 Make sure to set BRAINTRUST_API_KEY environment variable or pass token in Authorization header"
|
||||
)
|
||||
|
||||
uvicorn.run(app, host=host, port=port)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
|
|
@ -43,6 +43,14 @@ hide_table_of_contents: false
|
|||
## Key Highlights
|
||||
[3-5 bullet points of major features - prioritize MCP OAuth 2.0, scheduled key rotations, and major model updates]
|
||||
|
||||
## New Providers and Endpoints
|
||||
|
||||
### New Providers
|
||||
[Table with Provider, Supported Endpoints, Description columns]
|
||||
|
||||
### New LLM API Endpoints
|
||||
[Optional table for new endpoint additions with Endpoint, Method, Description, Documentation columns]
|
||||
|
||||
## New Models / Updated Models
|
||||
#### New Model Support
|
||||
[Model pricing table]
|
||||
|
|
@ -53,9 +61,6 @@ hide_table_of_contents: false
|
|||
### Bug Fixes
|
||||
[Provider-specific bug fixes organized by provider]
|
||||
|
||||
#### New Provider Support
|
||||
[New provider integrations]
|
||||
|
||||
## LLM API Endpoints
|
||||
#### Features
|
||||
[API-specific features organized by API type]
|
||||
|
|
@ -70,16 +75,20 @@ hide_table_of_contents: false
|
|||
#### Bugs
|
||||
[Management-related bug fixes]
|
||||
|
||||
## Logging / Guardrail / Prompt Management Integrations
|
||||
#### Features
|
||||
[Organized by integration provider with proper doc links]
|
||||
## AI Integrations
|
||||
|
||||
#### Guardrails
|
||||
### Logging
|
||||
[Logging integrations organized by provider with proper doc links, includes General subsection]
|
||||
|
||||
### Guardrails
|
||||
[Guardrail-specific features and fixes]
|
||||
|
||||
#### Prompt Management
|
||||
### Prompt Management
|
||||
[Prompt management integrations like BitBucket]
|
||||
|
||||
### Secret Managers
|
||||
[Secret manager integrations - AWS, HashiCorp Vault, CyberArk, etc.]
|
||||
|
||||
## Spend Tracking, Budgets and Rate Limiting
|
||||
[Cost tracking, service tier pricing, rate limiting improvements]
|
||||
|
||||
|
|
@ -149,26 +158,34 @@ hide_table_of_contents: false
|
|||
- Admin settings updates
|
||||
- Management routes and endpoints
|
||||
|
||||
**Logging / Guardrail / Prompt Management Integrations:**
|
||||
**AI Integrations:**
|
||||
- **Structure:**
|
||||
- `#### Features` - organized by integration provider with proper doc links
|
||||
- `#### Guardrails` - guardrail-specific features and fixes
|
||||
- `#### Prompt Management` - prompt management integrations
|
||||
- `#### New Integration` - major new integrations
|
||||
- **Integration Categories:**
|
||||
- `### Logging` - organized by integration provider with proper doc links, includes **General** subsection
|
||||
- `### Guardrails` - guardrail-specific features and fixes
|
||||
- `### Prompt Management` - prompt management integrations
|
||||
- `### Secret Managers` - secret manager integrations
|
||||
- **Logging Categories:**
|
||||
- **[DataDog](../../docs/proxy/logging#datadog)** - group all DataDog-related changes
|
||||
- **[Langfuse](../../docs/proxy/logging#langfuse)** - Langfuse-specific features
|
||||
- **[Prometheus](../../docs/proxy/logging#prometheus)** - monitoring improvements
|
||||
- **[PostHog](../../docs/observability/posthog)** - observability integration
|
||||
- **[SQS](../../docs/proxy/logging#sqs)** - SQS logging features
|
||||
- **[Opik](../../docs/proxy/logging#opik)** - Opik integration improvements
|
||||
- **[Arize Phoenix](../../docs/observability/arize_phoenix)** - Arize Phoenix integration
|
||||
- **General** - miscellaneous logging features like callback controls, sensitive data masking
|
||||
- Other logging providers with proper doc links
|
||||
- **Guardrail Categories:**
|
||||
- LakeraAI, Presidio, Noma, and other guardrail providers
|
||||
- LakeraAI, Presidio, Noma, Grayswan, IBM Guardrails, and other guardrail providers
|
||||
- **Prompt Management:**
|
||||
- BitBucket, GitHub, and other prompt management integrations
|
||||
- Prompt versioning, testing, and UI features
|
||||
- **Secret Managers:**
|
||||
- **[AWS Secrets Manager](../../docs/secret_managers)** - AWS secret manager features
|
||||
- **[HashiCorp Vault](../../docs/secret_managers)** - Vault integrations
|
||||
- **[CyberArk](../../docs/secret_managers)** - CyberArk integrations
|
||||
- **General** - cross-secret-manager features
|
||||
- Use bullet points under each provider for multiple features
|
||||
- Separate logging features from guardrails and prompt management clearly
|
||||
- Separate logging, guardrails, prompt management, and secret managers clearly
|
||||
|
||||
### 4. Documentation Linking Strategy
|
||||
|
||||
|
|
@ -232,6 +249,9 @@ From git diff analysis, create tables like:
|
|||
- **Cost breakdown in logging** → Spend Tracking section
|
||||
- **MCP configuration/OAuth** → MCP Gateway (NOT General Proxy Improvements)
|
||||
- **All documentation PRs** → Documentation Updates section for visibility
|
||||
- **Callback controls/logging features** → AI Integrations > Logging > General
|
||||
- **Secret manager features** → AI Integrations > Secret Managers
|
||||
- **Video generation tag-based routing** → LLM API Endpoints > Video Generation API
|
||||
|
||||
### 7. Writing Style Guidelines
|
||||
|
||||
|
|
@ -370,10 +390,107 @@ This release has a known issue...
|
|||
- **Virtual Keys** - Key rotation and management
|
||||
- **Models + Endpoints** - Provider and endpoint management
|
||||
|
||||
**Logging Section Expansion:**
|
||||
- Rename to "Logging / Guardrail / Prompt Management Integrations"
|
||||
- Add **Prompt Management** subsection for BitBucket, GitHub integrations
|
||||
- Keep guardrails separate from logging features
|
||||
**AI Integrations Section Expansion:**
|
||||
- Renamed from "Logging / Guardrail / Prompt Management Integrations" to "AI Integrations"
|
||||
- Structure with four main subsections:
|
||||
- **Logging** - with **General** subsection for miscellaneous logging features
|
||||
- **Guardrails** - separate from logging features
|
||||
- **Prompt Management** - BitBucket, GitHub integrations, versioning features
|
||||
- **Secret Managers** - AWS, HashiCorp Vault, CyberArk, etc.
|
||||
|
||||
**New Providers and Endpoints Section:**
|
||||
- Add section after Key Highlights and before New Models / Updated Models
|
||||
- Include tables for:
|
||||
- **New Providers** - Provider name, supported endpoints, description
|
||||
- **New LLM API Endpoints** (optional) - Endpoint, method, description, documentation link
|
||||
- Only include major new provider integrations, not minor provider updates
|
||||
- **IMPORTANT**: When adding new providers, also update `provider_endpoints_support.json` in the repository root (see Section 13)
|
||||
|
||||
### 12. Section Header Counts
|
||||
|
||||
**Always include counts in section headers for:**
|
||||
- **New Providers** - Add count in parentheses: `### New Providers (X new providers)`
|
||||
- **New LLM API Endpoints** - Add count in parentheses: `### New LLM API Endpoints (X new endpoints)`
|
||||
- **New Model Support** - Add count in parentheses: `#### New Model Support (X new models)`
|
||||
|
||||
**Format:**
|
||||
```markdown
|
||||
### New Providers (4 new providers)
|
||||
|
||||
| Provider | Supported LiteLLM Endpoints | Description |
|
||||
| -------- | --------------------------- | ----------- |
|
||||
...
|
||||
|
||||
### New LLM API Endpoints (2 new endpoints)
|
||||
|
||||
| Endpoint | Method | Description | Documentation |
|
||||
| -------- | ------ | ----------- | ------------- |
|
||||
...
|
||||
|
||||
#### New Model Support (32 new models)
|
||||
|
||||
| Provider | Model | Context Window | Input ($/1M tokens) | Output ($/1M tokens) | Features |
|
||||
| -------- | ----- | -------------- | ------------------- | -------------------- | -------- |
|
||||
...
|
||||
```
|
||||
|
||||
**Counting Rules:**
|
||||
- Count each row in the table (excluding the header row)
|
||||
- For models, count each model entry in the pricing table
|
||||
- For providers, count each new provider added
|
||||
- For endpoints, count each new API endpoint added
|
||||
|
||||
### 13. Update provider_endpoints_support.json
|
||||
|
||||
**When adding new providers or endpoints, you MUST also update `provider_endpoints_support.json` in the repository root.**
|
||||
|
||||
This file tracks which endpoints are supported by each LiteLLM provider and is used to generate documentation.
|
||||
|
||||
**Required Steps:**
|
||||
1. For each new provider added to the release notes, add a corresponding entry to `provider_endpoints_support.json`
|
||||
2. For each new endpoint type added, update the schema comment and add the endpoint to relevant providers
|
||||
|
||||
**Provider Entry Format:**
|
||||
```json
|
||||
"provider_slug": {
|
||||
"display_name": "Provider Name (`provider_slug`)",
|
||||
"url": "https://docs.litellm.ai/docs/providers/provider_slug",
|
||||
"endpoints": {
|
||||
"chat_completions": true,
|
||||
"messages": true,
|
||||
"responses": true,
|
||||
"embeddings": false,
|
||||
"image_generations": false,
|
||||
"audio_transcriptions": false,
|
||||
"audio_speech": false,
|
||||
"moderations": false,
|
||||
"batches": false,
|
||||
"rerank": false,
|
||||
"a2a": true
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Available Endpoint Types:**
|
||||
- `chat_completions` - `/chat/completions` endpoint
|
||||
- `messages` - `/messages` endpoint (Anthropic format)
|
||||
- `responses` - `/responses` endpoint (OpenAI/Anthropic unified)
|
||||
- `embeddings` - `/embeddings` endpoint
|
||||
- `image_generations` - `/image/generations` endpoint
|
||||
- `audio_transcriptions` - `/audio/transcriptions` endpoint
|
||||
- `audio_speech` - `/audio/speech` endpoint
|
||||
- `moderations` - `/moderations` endpoint
|
||||
- `batches` - `/batches` endpoint
|
||||
- `rerank` - `/rerank` endpoint
|
||||
- `ocr` - `/ocr` endpoint
|
||||
- `search` - `/search` endpoint
|
||||
- `vector_stores` - `/vector_stores` endpoint
|
||||
- `a2a` - `/a2a/{agent}/message/send` endpoint (A2A Protocol)
|
||||
|
||||
**Checklist:**
|
||||
- [ ] All new providers from release notes are added to `provider_endpoints_support.json`
|
||||
- [ ] Endpoint support flags accurately reflect provider capabilities
|
||||
- [ ] Documentation URL points to correct provider docs page
|
||||
|
||||
## Example Command Workflow
|
||||
|
||||
|
|
|
|||
540
cookbook/mock_guardrail_server/mock_bedrock_guardrail_server.py
Normal file
540
cookbook/mock_guardrail_server/mock_bedrock_guardrail_server.py
Normal file
|
|
@ -0,0 +1,540 @@
|
|||
#!/usr/bin/env python3
|
||||
"""
|
||||
Mock Bedrock Guardrail API Server
|
||||
|
||||
This is a FastAPI server that mimics the AWS Bedrock Guardrail API for testing purposes.
|
||||
It follows the same API spec as the real Bedrock guardrail endpoint.
|
||||
|
||||
Usage:
|
||||
python mock_bedrock_guardrail_server.py
|
||||
|
||||
The server will start on http://localhost:8080
|
||||
"""
|
||||
|
||||
import os
|
||||
import re
|
||||
from typing import Any, Dict, List, Literal, Optional
|
||||
|
||||
from fastapi import Depends, FastAPI, Header, HTTPException, status
|
||||
from fastapi.responses import JSONResponse
|
||||
from pydantic import BaseModel, Field
|
||||
|
||||
# ============================================================================
|
||||
# Request/Response Models (matching Bedrock API spec)
|
||||
# ============================================================================
|
||||
|
||||
|
||||
class BedrockTextContent(BaseModel):
|
||||
text: str
|
||||
|
||||
|
||||
class BedrockContentItem(BaseModel):
|
||||
text: BedrockTextContent
|
||||
|
||||
|
||||
class BedrockRequest(BaseModel):
|
||||
source: Literal["INPUT", "OUTPUT"]
|
||||
content: List[BedrockContentItem] = Field(default_factory=list)
|
||||
|
||||
|
||||
class BedrockGuardrailOutput(BaseModel):
|
||||
text: Optional[str] = None
|
||||
|
||||
|
||||
class TopicPolicyItem(BaseModel):
|
||||
name: str
|
||||
type: str
|
||||
action: Literal["BLOCKED", "NONE"]
|
||||
|
||||
|
||||
class TopicPolicy(BaseModel):
|
||||
topics: List[TopicPolicyItem] = Field(default_factory=list)
|
||||
|
||||
|
||||
class ContentFilterItem(BaseModel):
|
||||
type: str
|
||||
confidence: str
|
||||
action: Literal["BLOCKED", "NONE"]
|
||||
|
||||
|
||||
class ContentPolicy(BaseModel):
|
||||
filters: List[ContentFilterItem] = Field(default_factory=list)
|
||||
|
||||
|
||||
class CustomWord(BaseModel):
|
||||
match: str
|
||||
action: Literal["BLOCKED", "NONE"]
|
||||
|
||||
|
||||
class WordPolicy(BaseModel):
|
||||
customWords: List[CustomWord] = Field(default_factory=list)
|
||||
managedWordLists: List[Dict[str, Any]] = Field(default_factory=list)
|
||||
|
||||
|
||||
class PiiEntity(BaseModel):
|
||||
type: str
|
||||
match: str
|
||||
action: Literal["BLOCKED", "ANONYMIZED", "NONE"]
|
||||
|
||||
|
||||
class RegexMatch(BaseModel):
|
||||
name: str
|
||||
match: str
|
||||
regex: str
|
||||
action: Literal["BLOCKED", "ANONYMIZED", "NONE"]
|
||||
|
||||
|
||||
class SensitiveInformationPolicy(BaseModel):
|
||||
piiEntities: List[PiiEntity] = Field(default_factory=list)
|
||||
regexes: List[RegexMatch] = Field(default_factory=list)
|
||||
|
||||
|
||||
class ContextualGroundingFilter(BaseModel):
|
||||
type: str
|
||||
threshold: float
|
||||
score: float
|
||||
action: Literal["BLOCKED", "NONE"]
|
||||
|
||||
|
||||
class ContextualGroundingPolicy(BaseModel):
|
||||
filters: List[ContextualGroundingFilter] = Field(default_factory=list)
|
||||
|
||||
|
||||
class Assessment(BaseModel):
|
||||
topicPolicy: Optional[TopicPolicy] = None
|
||||
contentPolicy: Optional[ContentPolicy] = None
|
||||
wordPolicy: Optional[WordPolicy] = None
|
||||
sensitiveInformationPolicy: Optional[SensitiveInformationPolicy] = None
|
||||
contextualGroundingPolicy: Optional[ContextualGroundingPolicy] = None
|
||||
|
||||
|
||||
class BedrockGuardrailResponse(BaseModel):
|
||||
usage: Dict[str, int] = Field(
|
||||
default_factory=lambda: {"topicPolicyUnits": 1, "contentPolicyUnits": 1}
|
||||
)
|
||||
action: Literal["NONE", "GUARDRAIL_INTERVENED"] = "NONE"
|
||||
outputs: List[BedrockGuardrailOutput] = Field(default_factory=list)
|
||||
assessments: List[Assessment] = Field(default_factory=list)
|
||||
|
||||
|
||||
# ============================================================================
|
||||
# Mock Guardrail Configuration
|
||||
# ============================================================================
|
||||
|
||||
|
||||
class GuardrailConfig(BaseModel):
|
||||
"""Configuration for mock guardrail behavior"""
|
||||
|
||||
blocked_words: List[str] = Field(
|
||||
default_factory=lambda: ["offensive", "inappropriate", "badword"]
|
||||
)
|
||||
blocked_topics: List[str] = Field(default_factory=lambda: ["violence", "illegal"])
|
||||
pii_patterns: Dict[str, str] = Field(
|
||||
default_factory=lambda: {
|
||||
"EMAIL": r"\b[A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+\.[A-Z|a-z]{2,}\b",
|
||||
"PHONE": r"\b\d{3}[-.]?\d{3}[-.]?\d{4}\b",
|
||||
"SSN": r"\b\d{3}-\d{2}-\d{4}\b",
|
||||
"CREDIT_CARD": r"\b\d{4}[\s-]?\d{4}[\s-]?\d{4}[\s-]?\d{4}\b",
|
||||
}
|
||||
)
|
||||
anonymize_pii: bool = True # If True, ANONYMIZE PII; if False, BLOCK it
|
||||
bearer_token: str = "mock-bedrock-token-12345"
|
||||
|
||||
|
||||
# Global config
|
||||
GUARDRAIL_CONFIG = GuardrailConfig()
|
||||
|
||||
# ============================================================================
|
||||
# FastAPI App Setup
|
||||
# ============================================================================
|
||||
|
||||
app = FastAPI(
|
||||
title="Mock Bedrock Guardrail API",
|
||||
description="Mock server mimicking AWS Bedrock Guardrail API",
|
||||
version="1.0.0",
|
||||
)
|
||||
|
||||
|
||||
# ============================================================================
|
||||
# Authentication
|
||||
# ============================================================================
|
||||
|
||||
|
||||
async def verify_bearer_token(authorization: Optional[str] = Header(None)) -> str:
|
||||
"""
|
||||
Verify the Bearer token from the Authorization header.
|
||||
|
||||
Args:
|
||||
authorization: The Authorization header value
|
||||
|
||||
Returns:
|
||||
The token if valid
|
||||
|
||||
Raises:
|
||||
HTTPException: If token is missing or invalid
|
||||
"""
|
||||
if authorization is None:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED,
|
||||
detail="Missing Authorization header",
|
||||
headers={"WWW-Authenticate": "Bearer"},
|
||||
)
|
||||
|
||||
# Check if it's a Bearer token
|
||||
parts = authorization.split()
|
||||
print(f"parts: {parts}")
|
||||
if len(parts) != 2 or parts[0].lower() != "bearer":
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED,
|
||||
detail="Invalid Authorization header format. Expected: Bearer <token>",
|
||||
headers={"WWW-Authenticate": "Bearer"},
|
||||
)
|
||||
|
||||
token = parts[1]
|
||||
|
||||
# Verify token
|
||||
if token != GUARDRAIL_CONFIG.bearer_token:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_403_FORBIDDEN,
|
||||
detail="Invalid bearer token",
|
||||
)
|
||||
|
||||
return token
|
||||
|
||||
|
||||
# ============================================================================
|
||||
# Guardrail Logic
|
||||
# ============================================================================
|
||||
|
||||
|
||||
def check_blocked_words(text: str) -> Optional[WordPolicy]:
|
||||
"""Check if text contains blocked words"""
|
||||
found_words = []
|
||||
text_lower = text.lower()
|
||||
|
||||
for word in GUARDRAIL_CONFIG.blocked_words:
|
||||
if word.lower() in text_lower:
|
||||
found_words.append(CustomWord(match=word, action="BLOCKED"))
|
||||
|
||||
if found_words:
|
||||
return WordPolicy(customWords=found_words)
|
||||
return None
|
||||
|
||||
|
||||
def check_blocked_topics(text: str) -> Optional[TopicPolicy]:
|
||||
"""Check if text contains blocked topics"""
|
||||
found_topics = []
|
||||
text_lower = text.lower()
|
||||
|
||||
for topic in GUARDRAIL_CONFIG.blocked_topics:
|
||||
if topic.lower() in text_lower:
|
||||
found_topics.append(
|
||||
TopicPolicyItem(name=topic, type=topic.upper(), action="BLOCKED")
|
||||
)
|
||||
|
||||
if found_topics:
|
||||
return TopicPolicy(topics=found_topics)
|
||||
return None
|
||||
|
||||
|
||||
def check_pii(text: str) -> tuple[Optional[SensitiveInformationPolicy], str]:
|
||||
"""
|
||||
Check for PII in text and return policy + anonymized text
|
||||
|
||||
Returns:
|
||||
Tuple of (SensitiveInformationPolicy or None, anonymized_text)
|
||||
"""
|
||||
pii_entities = []
|
||||
anonymized_text = text
|
||||
action = "ANONYMIZED" if GUARDRAIL_CONFIG.anonymize_pii else "BLOCKED"
|
||||
|
||||
for pii_type, pattern in GUARDRAIL_CONFIG.pii_patterns.items():
|
||||
try:
|
||||
# Compile the regex pattern with a timeout to prevent ReDoS attacks
|
||||
compiled_pattern = re.compile(pattern)
|
||||
matches = compiled_pattern.finditer(text)
|
||||
for match in matches:
|
||||
matched_text = match.group()
|
||||
pii_entities.append(
|
||||
PiiEntity(type=pii_type, match=matched_text, action=action)
|
||||
)
|
||||
|
||||
# Anonymize the text if configured
|
||||
if GUARDRAIL_CONFIG.anonymize_pii:
|
||||
anonymized_text = anonymized_text.replace(
|
||||
matched_text, f"[{pii_type}_REDACTED]"
|
||||
)
|
||||
except re.error:
|
||||
# Invalid regex pattern - skip it and log a warning
|
||||
print(f"Warning: Invalid regex pattern for PII type {pii_type}: {pattern}")
|
||||
continue
|
||||
|
||||
if pii_entities:
|
||||
return SensitiveInformationPolicy(piiEntities=pii_entities), anonymized_text
|
||||
|
||||
return None, text
|
||||
|
||||
|
||||
def process_guardrail_request(
|
||||
request: BedrockRequest,
|
||||
) -> tuple[BedrockGuardrailResponse, List[str]]:
|
||||
"""
|
||||
Process a guardrail request and return the response.
|
||||
|
||||
Returns:
|
||||
Tuple of (response, list of output texts)
|
||||
"""
|
||||
all_text_content = []
|
||||
output_texts = []
|
||||
|
||||
# Extract all text from content items
|
||||
for content_item in request.content:
|
||||
if content_item.text and content_item.text.text:
|
||||
all_text_content.append(content_item.text.text)
|
||||
|
||||
# Combine all text for analysis
|
||||
combined_text = " ".join(all_text_content)
|
||||
|
||||
# Initialize response
|
||||
response = BedrockGuardrailResponse()
|
||||
assessment = Assessment()
|
||||
has_intervention = False
|
||||
|
||||
# Check for blocked words
|
||||
word_policy = check_blocked_words(combined_text)
|
||||
if word_policy:
|
||||
assessment.wordPolicy = word_policy
|
||||
has_intervention = True
|
||||
|
||||
# Check for blocked topics
|
||||
topic_policy = check_blocked_topics(combined_text)
|
||||
if topic_policy:
|
||||
assessment.topicPolicy = topic_policy
|
||||
has_intervention = True
|
||||
|
||||
# Check for PII
|
||||
for text in all_text_content:
|
||||
pii_policy, anonymized_text = check_pii(text)
|
||||
if pii_policy:
|
||||
assessment.sensitiveInformationPolicy = pii_policy
|
||||
if GUARDRAIL_CONFIG.anonymize_pii:
|
||||
# If anonymizing, we don't block, we modify the text
|
||||
output_texts.append(anonymized_text)
|
||||
has_intervention = True
|
||||
else:
|
||||
# If not anonymizing PII, we block it
|
||||
output_texts.append(text)
|
||||
has_intervention = True
|
||||
else:
|
||||
output_texts.append(text)
|
||||
|
||||
# Build response
|
||||
if has_intervention:
|
||||
response.action = "GUARDRAIL_INTERVENED"
|
||||
# Only add assessment if there were interventions
|
||||
response.assessments = [assessment]
|
||||
|
||||
# Add outputs (modified or original text)
|
||||
response.outputs = [BedrockGuardrailOutput(text=txt) for txt in output_texts]
|
||||
|
||||
return response, output_texts
|
||||
|
||||
|
||||
# ============================================================================
|
||||
# API Endpoints
|
||||
# ============================================================================
|
||||
|
||||
|
||||
@app.get("/")
|
||||
async def root():
|
||||
"""Health check endpoint"""
|
||||
return {
|
||||
"service": "Mock Bedrock Guardrail API",
|
||||
"status": "running",
|
||||
"endpoint_format": "/guardrail/{guardrailIdentifier}/version/{guardrailVersion}/apply",
|
||||
}
|
||||
|
||||
|
||||
@app.get("/health")
|
||||
async def health():
|
||||
"""Health check endpoint"""
|
||||
return {"status": "healthy"}
|
||||
|
||||
|
||||
"""
|
||||
LiteLLM exposes a basic guardrail API with the text extracted from the request and sent to the guardrail API, as well as the received request body for any further processing.
|
||||
|
||||
This works across all LiteLLM endpoints (completion, anthropic /v1/messages, responses api, image generation, embedding, etc.)
|
||||
|
||||
This makes it easy to support your own guardrail API without having to make a PR to LiteLLM.
|
||||
|
||||
LiteLLM supports passing any provider specific params from LiteLLM config.yaml to the guardrail API.
|
||||
|
||||
Example:
|
||||
|
||||
```yaml
|
||||
guardrails:
|
||||
- guardrail_name: "bedrock-content-guard"
|
||||
litellm_params:
|
||||
guardrail: generic_guardrail_api
|
||||
mode: "pre_call"
|
||||
api_key: os.environ/GUARDRAIL_API_KEY
|
||||
api_base: os.environ/GUARDRAIL_API_BASE
|
||||
additional_provider_specific_params:
|
||||
api_version: os.environ/GUARDRAIL_API_VERSION # additional provider specific params
|
||||
```
|
||||
|
||||
This is a beta API. Please help us improve it.
|
||||
"""
|
||||
|
||||
|
||||
class LitellmBasicGuardrailRequest(BaseModel):
|
||||
texts: List[str]
|
||||
images: Optional[List[str]] = None
|
||||
tools: Optional[List[dict]] = None
|
||||
tool_calls: Optional[List[dict]] = None
|
||||
request_data: Dict[str, Any] = Field(default_factory=dict)
|
||||
additional_provider_specific_params: Dict[str, Any] = Field(default_factory=dict)
|
||||
input_type: Literal["request", "response"]
|
||||
litellm_call_id: Optional[str] = None
|
||||
litellm_trace_id: Optional[str] = None
|
||||
structured_messages: Optional[List[Dict[str, Any]]] = None
|
||||
|
||||
|
||||
class LitellmBasicGuardrailResponse(BaseModel):
|
||||
action: Literal[
|
||||
"BLOCKED", "NONE", "GUARDRAIL_INTERVENED"
|
||||
] # BLOCKED = litellm will raise an error, NONE = litellm will continue, GUARDRAIL_INTERVENED = litellm will continue, but the text was modified by the guardrail
|
||||
blocked_reason: Optional[str] = None # only if action is BLOCKED, otherwise None
|
||||
texts: Optional[List[str]] = None
|
||||
images: Optional[List[str]] = None
|
||||
|
||||
|
||||
@app.post(
|
||||
"/beta/litellm_basic_guardrail_api",
|
||||
response_model=LitellmBasicGuardrailResponse,
|
||||
)
|
||||
async def beta_litellm_basic_guardrail_api(
|
||||
request: LitellmBasicGuardrailRequest,
|
||||
) -> LitellmBasicGuardrailResponse:
|
||||
"""
|
||||
Apply guardrail to input or output content.
|
||||
|
||||
This endpoint mimics the AWS Bedrock ApplyGuardrail API.
|
||||
|
||||
Args:
|
||||
request: The guardrail request containing content to analyze
|
||||
token: Bearer token (verified by dependency)
|
||||
|
||||
Returns:
|
||||
LitellmBasicGuardrailResponse with analysis results
|
||||
"""
|
||||
print(f"request: {request}")
|
||||
if any("ishaan" in text.lower() for text in request.texts):
|
||||
return LitellmBasicGuardrailResponse(
|
||||
action="BLOCKED", blocked_reason="Ishaan is not allowed"
|
||||
)
|
||||
elif any("pii_value" in text for text in request.texts):
|
||||
return LitellmBasicGuardrailResponse(
|
||||
action="GUARDRAIL_INTERVENED",
|
||||
texts=[
|
||||
text.replace("pii_value", "pii_value_redacted")
|
||||
for text in request.texts
|
||||
],
|
||||
)
|
||||
return LitellmBasicGuardrailResponse(action="NONE")
|
||||
|
||||
|
||||
@app.post("/config/update")
|
||||
async def update_config(
|
||||
config: GuardrailConfig, token: str = Depends(verify_bearer_token)
|
||||
):
|
||||
"""
|
||||
Update the guardrail configuration.
|
||||
|
||||
This is a testing endpoint to modify the mock guardrail behavior.
|
||||
|
||||
Args:
|
||||
config: New guardrail configuration
|
||||
token: Bearer token (verified by dependency)
|
||||
|
||||
Returns:
|
||||
Updated configuration
|
||||
"""
|
||||
global GUARDRAIL_CONFIG
|
||||
GUARDRAIL_CONFIG = config
|
||||
return {"status": "updated", "config": GUARDRAIL_CONFIG}
|
||||
|
||||
|
||||
@app.get("/config")
|
||||
async def get_config(token: str = Depends(verify_bearer_token)):
|
||||
"""
|
||||
Get the current guardrail configuration.
|
||||
|
||||
Args:
|
||||
token: Bearer token (verified by dependency)
|
||||
|
||||
Returns:
|
||||
Current configuration
|
||||
"""
|
||||
return GUARDRAIL_CONFIG
|
||||
|
||||
|
||||
# ============================================================================
|
||||
# Error Handlers
|
||||
# ============================================================================
|
||||
|
||||
|
||||
@app.exception_handler(HTTPException)
|
||||
async def http_exception_handler(request, exc: HTTPException):
|
||||
"""Custom error handler for HTTP exceptions"""
|
||||
return JSONResponse(
|
||||
status_code=exc.status_code,
|
||||
content={"error": exc.detail},
|
||||
headers=exc.headers,
|
||||
)
|
||||
|
||||
|
||||
# ============================================================================
|
||||
# Main
|
||||
# ============================================================================
|
||||
|
||||
if __name__ == "__main__":
|
||||
import uvicorn
|
||||
|
||||
# Get configuration from environment
|
||||
host = os.getenv("MOCK_BEDROCK_HOST", "0.0.0.0")
|
||||
port = int(os.getenv("MOCK_BEDROCK_PORT", "8080"))
|
||||
bearer_token = os.getenv("MOCK_BEDROCK_TOKEN", "mock-bedrock-token-12345")
|
||||
|
||||
# Update config with environment token
|
||||
GUARDRAIL_CONFIG.bearer_token = bearer_token
|
||||
|
||||
print("=" * 80)
|
||||
print("Mock Bedrock Guardrail API Server")
|
||||
print("=" * 80)
|
||||
print(f"Server starting on: http://{host}:{port}")
|
||||
print(f"Bearer Token: {bearer_token}")
|
||||
print(f"Endpoint: POST /guardrail/{{id}}/version/{{version}}/apply")
|
||||
print("=" * 80)
|
||||
print("\nExample curl command:")
|
||||
print(
|
||||
f"""
|
||||
curl -X POST "http://{host}:{port}/guardrail/test-guardrail/version/1/apply" \\
|
||||
-H "Authorization: Bearer {bearer_token}" \\
|
||||
-H "Content-Type: application/json" \\
|
||||
-d '{{
|
||||
"source": "INPUT",
|
||||
"content": [
|
||||
{{
|
||||
"text": {{
|
||||
"text": "Hello, my email is test@example.com"
|
||||
}}
|
||||
}}
|
||||
]
|
||||
}}'
|
||||
"""
|
||||
)
|
||||
print("=" * 80)
|
||||
|
||||
uvicorn.run(app, host=host, port=port)
|
||||
|
|
@ -18,7 +18,7 @@ type: application
|
|||
# This is the chart version. This version number should be incremented each time you make changes
|
||||
# to the chart and its templates, including the app version.
|
||||
# Versions are expected to follow Semantic Versioning (https://semver.org/)
|
||||
version: 0.4.7
|
||||
version: 0.4.10
|
||||
|
||||
# This is the version number of the application being deployed. This version number should be
|
||||
# incremented each time you make changes to the application. Versions are not expected to
|
||||
|
|
@ -33,5 +33,5 @@ dependencies:
|
|||
condition: db.deployStandalone
|
||||
- name: redis
|
||||
version: ">=18.0.0"
|
||||
repository: oci://registry-1.docker.io/bitnamicharts
|
||||
repository: oci://registry-1.docker.io/bitnamicharts
|
||||
condition: redis.enabled
|
||||
|
|
|
|||
|
|
@ -10,46 +10,48 @@
|
|||
- Helm 3.8.0+
|
||||
|
||||
If `db.deployStandalone` is used:
|
||||
|
||||
- PV provisioner support in the underlying infrastructure
|
||||
|
||||
If `db.useStackgresOperator` is used (not yet implemented):
|
||||
- The Stackgres Operator must already be installed in the Kubernetes Cluster. This chart will **not** install the operator if it is missing.
|
||||
|
||||
- The Stackgres Operator must already be installed in the Kubernetes Cluster. This chart will **not** install the operator if it is missing.
|
||||
|
||||
## Parameters
|
||||
|
||||
### LiteLLM Proxy Deployment Settings
|
||||
|
||||
| Name | Description | Value |
|
||||
| ---------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----- |
|
||||
| `replicaCount` | The number of LiteLLM Proxy pods to be deployed | `1` |
|
||||
| `masterkeySecretName` | The name of the Kubernetes Secret that contains the Master API Key for LiteLLM. If not specified, use the generated secret name. | N/A |
|
||||
| `masterkeySecretKey` | The key within the Kubernetes Secret that contains the Master API Key for LiteLLM. If not specified, use `masterkey` as the key. | N/A |
|
||||
| `masterkey` | The Master API Key for LiteLLM. If not specified, a random key in the `sk-...` format is generated. | N/A |
|
||||
| `environmentSecrets` | An optional array of Secret object names. The keys and values in these secrets will be presented to the LiteLLM proxy pod as environment variables. See below for an example Secret object. | `[]` |
|
||||
| `environmentConfigMaps` | An optional array of ConfigMap object names. The keys and values in these configmaps will be presented to the LiteLLM proxy pod as environment variables. See below for an example Secret object. | `[]` |
|
||||
| `image.repository` | LiteLLM Proxy image repository | `ghcr.io/berriai/litellm` |
|
||||
| `image.pullPolicy` | LiteLLM Proxy image pull policy | `IfNotPresent` |
|
||||
| `image.tag` | Overrides the image tag whose default the latest version of LiteLLM at the time this chart was published. | `""` |
|
||||
| `imagePullSecrets` | Registry credentials for the LiteLLM and initContainer images. | `[]` |
|
||||
| `serviceAccount.create` | Whether or not to create a Kubernetes Service Account for this deployment. The default is `false` because LiteLLM has no need to access the Kubernetes API. | `false` |
|
||||
| `service.type` | Kubernetes Service type (e.g. `LoadBalancer`, `ClusterIP`, etc.) | `ClusterIP` |
|
||||
| `service.port` | TCP port that the Kubernetes Service will listen on. Also the TCP port within the Pod that the proxy will listen on. | `4000` |
|
||||
| `service.loadBalancerClass` | Optional LoadBalancer implementation class (only used when `service.type` is `LoadBalancer`) | `""` |
|
||||
| `ingress.*` | See [values.yaml](./values.yaml) for example settings | N/A |
|
||||
| `proxyConfigMap.create` | When `true`, render a ConfigMap from `.Values.proxy_config` and mount it. | `true` |
|
||||
| `proxyConfigMap.name` | When `create=false`, name of the existing ConfigMap to mount. | `""` |
|
||||
| `proxyConfigMap.key` | Key in the ConfigMap that contains the proxy config file. | `"config.yaml"` |
|
||||
| `proxy_config.*` | See [values.yaml](./values.yaml) for default settings. Rendered into the ConfigMap’s `config.yaml` only when `proxyConfigMap.create=true`. See [example_config_yaml](../../../litellm/proxy/example_config_yaml/) for configuration examples. | `N/A` |
|
||||
| `extraContainers[]` | An array of additional containers to be deployed as sidecars alongside the LiteLLM Proxy.
|
||||
| `pdb.enabled` | Enable a PodDisruptionBudget for the LiteLLM proxy Deployment | `false` |
|
||||
| `pdb.minAvailable` | Minimum number/percentage of pods that must be available during **voluntary** disruptions (choose **one** of minAvailable/maxUnavailable) | `null` |
|
||||
| `pdb.maxUnavailable` | Maximum number/percentage of pods that can be unavailable during **voluntary** disruptions (choose **one** of minAvailable/maxUnavailable) | `null` |
|
||||
| `pdb.annotations` | Extra metadata annotations to add to the PDB | `{}` |
|
||||
| `pdb.labels` | Extra metadata labels to add to the PDB | `{}` |
|
||||
| Name | Description | Value |
|
||||
| --------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------- |
|
||||
| `replicaCount` | The number of LiteLLM Proxy pods to be deployed | `1` |
|
||||
| `masterkeySecretName` | The name of the Kubernetes Secret that contains the Master API Key for LiteLLM. If not specified, use the generated secret name. | N/A |
|
||||
| `masterkeySecretKey` | The key within the Kubernetes Secret that contains the Master API Key for LiteLLM. If not specified, use `masterkey` as the key. | N/A |
|
||||
| `masterkey` | The Master API Key for LiteLLM. If not specified, a random key in the `sk-...` format is generated. | N/A |
|
||||
| `environmentSecrets` | An optional array of Secret object names. The keys and values in these secrets will be presented to the LiteLLM proxy pod as environment variables. See below for an example Secret object. | `[]` |
|
||||
| `environmentConfigMaps` | An optional array of ConfigMap object names. The keys and values in these configmaps will be presented to the LiteLLM proxy pod as environment variables. See below for an example Secret object. | `[]` |
|
||||
| `image.repository` | LiteLLM Proxy image repository | `ghcr.io/berriai/litellm` |
|
||||
| `image.pullPolicy` | LiteLLM Proxy image pull policy | `IfNotPresent` |
|
||||
| `image.tag` | Overrides the image tag whose default the latest version of LiteLLM at the time this chart was published. | `""` |
|
||||
| `imagePullSecrets` | Registry credentials for the LiteLLM and initContainer images. | `[]` |
|
||||
| `serviceAccount.create` | Whether or not to create a Kubernetes Service Account for this deployment. The default is `false` because LiteLLM has no need to access the Kubernetes API. | `false` |
|
||||
| `service.type` | Kubernetes Service type (e.g. `LoadBalancer`, `ClusterIP`, etc.) | `ClusterIP` |
|
||||
| `service.port` | TCP port that the Kubernetes Service will listen on. Also the TCP port within the Pod that the proxy will listen on. | `4000` |
|
||||
| `service.loadBalancerClass` | Optional LoadBalancer implementation class (only used when `service.type` is `LoadBalancer`) | `""` |
|
||||
| `ingress.labels` | Additional labels for the Ingress resource | `{}` |
|
||||
| `ingress.*` | See [values.yaml](./values.yaml) for example settings | N/A |
|
||||
| `proxyConfigMap.create` | When `true`, render a ConfigMap from `.Values.proxy_config` and mount it. | `true` |
|
||||
| `proxyConfigMap.name` | When `create=false`, name of the existing ConfigMap to mount. | `""` |
|
||||
| `proxyConfigMap.key` | Key in the ConfigMap that contains the proxy config file. | `"config.yaml"` |
|
||||
| `proxy_config.*` | See [values.yaml](./values.yaml) for default settings. Rendered into the ConfigMap’s `config.yaml` only when `proxyConfigMap.create=true`. See [example_config_yaml](../../../litellm/proxy/example_config_yaml/) for configuration examples. | `N/A` |
|
||||
| `extraContainers[]` | An array of additional containers to be deployed as sidecars alongside the LiteLLM Proxy. |
|
||||
| `pdb.enabled` | Enable a PodDisruptionBudget for the LiteLLM proxy Deployment | `false` |
|
||||
| `pdb.minAvailable` | Minimum number/percentage of pods that must be available during **voluntary** disruptions (choose **one** of minAvailable/maxUnavailable) | `null` |
|
||||
| `pdb.maxUnavailable` | Maximum number/percentage of pods that can be unavailable during **voluntary** disruptions (choose **one** of minAvailable/maxUnavailable) | `null` |
|
||||
| `pdb.annotations` | Extra metadata annotations to add to the PDB | `{}` |
|
||||
| `pdb.labels` | Extra metadata labels to add to the PDB | `{}` |
|
||||
|
||||
#### Example `proxy_config` ConfigMap from values (default):
|
||||
|
||||
|
||||
```
|
||||
proxyConfigMap:
|
||||
create: true
|
||||
|
|
@ -67,7 +69,6 @@ proxy_config:
|
|||
|
||||
#### Example using existing `proxyConfigMap` instead of creating it:
|
||||
|
||||
|
||||
```
|
||||
proxyConfigMap:
|
||||
create: false
|
||||
|
|
@ -77,8 +78,7 @@ proxyConfigMap:
|
|||
# proxy_config is ignored in this mode
|
||||
```
|
||||
|
||||
#### Example `environmentSecrets` Secret
|
||||
|
||||
#### Example `environmentSecrets` Secret
|
||||
|
||||
```
|
||||
apiVersion: v1
|
||||
|
|
@ -91,21 +91,23 @@ type: Opaque
|
|||
```
|
||||
|
||||
### Database Settings
|
||||
| Name | Description | Value |
|
||||
| ---------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----- |
|
||||
| `db.useExisting` | Use an existing Postgres database. A Kubernetes Secret object must exist that contains credentials for connecting to the database. An example secret object definition is provided below. | `false` |
|
||||
| `db.endpoint` | If `db.useExisting` is `true`, this is the IP, Hostname or Service Name of the Postgres server to connect to. | `localhost` |
|
||||
| `db.database` | If `db.useExisting` is `true`, the name of the existing database to connect to. | `litellm` |
|
||||
| `db.url` | If `db.useExisting` is `true`, the connection url of the existing database to connect to can be overwritten with this value. | `postgresql://$(DATABASE_USERNAME):$(DATABASE_PASSWORD)@$(DATABASE_HOST)/$(DATABASE_NAME)` |
|
||||
| `db.secret.name` | If `db.useExisting` is `true`, the name of the Kubernetes Secret that contains credentials. | `postgres` |
|
||||
| `db.secret.usernameKey` | If `db.useExisting` is `true`, the name of the key within the Kubernetes Secret that holds the username for authenticating with the Postgres instance. | `username` |
|
||||
| `db.secret.passwordKey` | If `db.useExisting` is `true`, the name of the key within the Kubernetes Secret that holds the password associates with the above user. | `password` |
|
||||
| `db.useStackgresOperator` | Not yet implemented. | `false` |
|
||||
| `db.deployStandalone` | Deploy a standalone, single instance deployment of Postgres, using the Bitnami postgresql chart. This is useful for getting started but doesn't provide HA or (by default) data backups. | `true` |
|
||||
| `postgresql.*` | If `db.deployStandalone` is `true`, configuration passed to the Bitnami postgresql chart. See the [Bitnami Documentation](https://github.com/bitnami/charts/tree/main/bitnami/postgresql) for full configuration details. See [values.yaml](./values.yaml) for the default configuration. | See [values.yaml](./values.yaml) |
|
||||
| `postgresql.auth.*` | If `db.deployStandalone` is `true`, care should be taken to ensure the default `password` and `postgres-password` values are **NOT** used. | `NoTaGrEaTpAsSwOrD` |
|
||||
|
||||
| Name | Description | Value |
|
||||
| ------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------ |
|
||||
| `db.useExisting` | Use an existing Postgres database. A Kubernetes Secret object must exist that contains credentials for connecting to the database. An example secret object definition is provided below. | `false` |
|
||||
| `db.endpoint` | If `db.useExisting` is `true`, this is the IP, Hostname or Service Name of the Postgres server to connect to. | `localhost` |
|
||||
| `db.database` | If `db.useExisting` is `true`, the name of the existing database to connect to. | `litellm` |
|
||||
| `db.url` | If `db.useExisting` is `true`, the connection url of the existing database to connect to can be overwritten with this value. | `postgresql://$(DATABASE_USERNAME):$(DATABASE_PASSWORD)@$(DATABASE_HOST)/$(DATABASE_NAME)` |
|
||||
| `db.secret.name` | If `db.useExisting` is `true`, the name of the Kubernetes Secret that contains credentials. | `postgres` |
|
||||
| `db.secret.usernameKey` | If `db.useExisting` is `true`, the name of the key within the Kubernetes Secret that holds the username for authenticating with the Postgres instance. | `username` |
|
||||
| `db.secret.passwordKey` | If `db.useExisting` is `true`, the name of the key within the Kubernetes Secret that holds the password associates with the above user. | `password` |
|
||||
| `db.useStackgresOperator` | Not yet implemented. | `false` |
|
||||
| `db.deployStandalone` | Deploy a standalone, single instance deployment of Postgres, using the Bitnami postgresql chart. This is useful for getting started but doesn't provide HA or (by default) data backups. | `true` |
|
||||
| `postgresql.*` | If `db.deployStandalone` is `true`, configuration passed to the Bitnami postgresql chart. See the [Bitnami Documentation](https://github.com/bitnami/charts/tree/main/bitnami/postgresql) for full configuration details. See [values.yaml](./values.yaml) for the default configuration. | See [values.yaml](./values.yaml) |
|
||||
| `postgresql.auth.*` | If `db.deployStandalone` is `true`, care should be taken to ensure the default `password` and `postgres-password` values are **NOT** used. | `NoTaGrEaTpAsSwOrD` |
|
||||
|
||||
#### Example Postgres `db.useExisting` Secret
|
||||
|
||||
```yaml
|
||||
apiVersion: v1
|
||||
kind: Secret
|
||||
|
|
@ -143,7 +145,7 @@ metadata:
|
|||
name: litellm-env-secret
|
||||
type: Opaque
|
||||
data:
|
||||
SOME_PASSWORD: cDZbUGVXeU5e0ZW # base64 encoded
|
||||
SOME_PASSWORD: cDZbUGVXeU5e0ZW # base64 encoded
|
||||
ANOTHER_PASSWORD: AAZbUGVXeU5e0ZB # base64 encoded
|
||||
```
|
||||
|
||||
|
|
@ -153,23 +155,23 @@ Source: [GitHub Gist from troyharvey](https://gist.github.com/troyharvey/4506472
|
|||
|
||||
The migration job supports both ArgoCD and Helm hooks to ensure database migrations run at the appropriate time during deployments.
|
||||
|
||||
| Name | Description | Value |
|
||||
| ---------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----- |
|
||||
| `migrationJob.enabled` | Enable or disable the schema migration Job | `true` |
|
||||
| `migrationJob.backoffLimit` | Backoff limit for Job restarts | `4` |
|
||||
| `migrationJob.ttlSecondsAfterFinished` | TTL for completed migration jobs | `120` |
|
||||
| `migrationJob.annotations` | Additional annotations for the migration job pod | `{}` |
|
||||
| `migrationJob.extraContainers` | Additional containers to run alongside the migration job | `[]` |
|
||||
| `migrationJob.hooks.argocd.enabled` | Enable ArgoCD hooks for the migration job (uses PreSync hook with BeforeHookCreation delete policy) | `true` |
|
||||
| `migrationJob.hooks.helm.enabled` | Enable Helm hooks for the migration job (uses pre-install,pre-upgrade hooks with before-hook-creation delete policy) | `false` |
|
||||
| `migrationJob.hooks.helm.weight` | Helm hook execution order (lower weights executed first). Optional - defaults to "1" if not specified. | N/A |
|
||||
|
||||
| Name | Description | Value |
|
||||
| -------------------------------------- | -------------------------------------------------------------------------------------------------------------------- | ------- |
|
||||
| `migrationJob.enabled` | Enable or disable the schema migration Job | `true` |
|
||||
| `migrationJob.backoffLimit` | Backoff limit for Job restarts | `4` |
|
||||
| `migrationJob.ttlSecondsAfterFinished` | TTL for completed migration jobs | `120` |
|
||||
| `migrationJob.annotations` | Additional annotations for the migration job pod | `{}` |
|
||||
| `migrationJob.extraContainers` | Additional containers to run alongside the migration job | `[]` |
|
||||
| `migrationJob.hooks.argocd.enabled` | Enable ArgoCD hooks for the migration job (uses PreSync hook with BeforeHookCreation delete policy) | `true` |
|
||||
| `migrationJob.hooks.helm.enabled` | Enable Helm hooks for the migration job (uses pre-install,pre-upgrade hooks with before-hook-creation delete policy) | `false` |
|
||||
| `migrationJob.hooks.helm.weight` | Helm hook execution order (lower weights executed first). Optional - defaults to "1" if not specified. | N/A |
|
||||
|
||||
## Accessing the Admin UI
|
||||
|
||||
When browsing to the URL published per the settings in `ingress.*`, you will
|
||||
be prompted for **Admin Configuration**. The **Proxy Endpoint** is the internal
|
||||
be prompted for **Admin Configuration**. The **Proxy Endpoint** is the internal
|
||||
(from the `litellm` pod's perspective) URL published by the `<RELEASE>-litellm`
|
||||
Kubernetes Service. If the deployment uses the default settings for this
|
||||
Kubernetes Service. If the deployment uses the default settings for this
|
||||
service, the **Proxy Endpoint** should be set to `http://<RELEASE>-litellm:4000`.
|
||||
|
||||
The **Proxy Key** is the value specified for `masterkey` or, if a `masterkey`
|
||||
|
|
@ -181,7 +183,8 @@ kubectl -n litellm get secret <RELEASE>-litellm-masterkey -o jsonpath="{.data.ma
|
|||
```
|
||||
|
||||
## Admin UI Limitations
|
||||
At the time of writing, the Admin UI is unable to add models. This is because
|
||||
|
||||
At the time of writing, the Admin UI is unable to add models. This is because
|
||||
it would need to update the `config.yaml` file which is a exposed ConfigMap, and
|
||||
therefore, read-only. This is a limitation of this helm chart, not the Admin UI
|
||||
therefore, read-only. This is a limitation of this helm chart, not the Admin UI
|
||||
itself.
|
||||
|
|
|
|||
|
|
@ -6,6 +6,9 @@ metadata:
|
|||
name: {{ include "litellm.fullname" . }}
|
||||
labels:
|
||||
{{- include "litellm.labels" . | nindent 4 }}
|
||||
{{- if .Values.deploymentLabels }}
|
||||
{{- toYaml .Values.deploymentLabels | nindent 4 }}
|
||||
{{- end }}
|
||||
spec:
|
||||
{{- if not .Values.autoscaling.enabled }}
|
||||
replicas: {{ .Values.replicaCount }}
|
||||
|
|
@ -126,9 +129,20 @@ spec:
|
|||
- configMapRef:
|
||||
name: {{ . }}
|
||||
{{- end }}
|
||||
{{- if .Values.command }}
|
||||
command: {{ toYaml .Values.command | nindent 12 }}
|
||||
{{- end }}
|
||||
{{- if .Values.args }}
|
||||
args: {{ toYaml .Values.args | nindent 12 }}
|
||||
{{- else }}
|
||||
args:
|
||||
- --config
|
||||
- /etc/litellm/config.yaml
|
||||
{{ if .Values.numWorkers }}
|
||||
- --num_workers
|
||||
- {{ .Values.numWorkers | quote }}
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
ports:
|
||||
- name: http
|
||||
containerPort: {{ .Values.service.port }}
|
||||
|
|
@ -208,3 +222,8 @@ spec:
|
|||
tolerations:
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- end }}
|
||||
terminationGracePeriodSeconds: {{ .Values.terminationGracePeriodSeconds | default 90 }}
|
||||
{{- if .Values.topologySpreadConstraints }}
|
||||
topologySpreadConstraints:
|
||||
{{- toYaml .Values.topologySpreadConstraints | nindent 8 }}
|
||||
{{- end }}
|
||||
|
|
@ -0,0 +1,6 @@
|
|||
{{- if .Values.extraResources }}
|
||||
{{- range .Values.extraResources }}
|
||||
---
|
||||
{{ toYaml . | nindent 0 }}
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
|
|
@ -18,6 +18,9 @@ metadata:
|
|||
name: {{ $fullName }}
|
||||
labels:
|
||||
{{- include "litellm.labels" . | nindent 4 }}
|
||||
{{- with .Values.ingress.labels }}
|
||||
{{- toYaml . | nindent 4 }}
|
||||
{{- end }}
|
||||
{{- with .Values.ingress.annotations }}
|
||||
annotations:
|
||||
{{- toYaml . | nindent 4 }}
|
||||
|
|
|
|||
|
|
@ -22,6 +22,9 @@ spec:
|
|||
metadata:
|
||||
labels:
|
||||
{{- include "litellm.labels" . | nindent 8 }}
|
||||
{{- with .Values.podLabels }}
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- end }}
|
||||
annotations:
|
||||
{{- with .Values.migrationJob.annotations }}
|
||||
{{- toYaml . | nindent 8 }}
|
||||
|
|
|
|||
39
deploy/charts/litellm-helm/templates/servicemonitor.yaml
Normal file
39
deploy/charts/litellm-helm/templates/servicemonitor.yaml
Normal file
|
|
@ -0,0 +1,39 @@
|
|||
{{- with .Values.serviceMonitor }}
|
||||
{{- if and (eq .enabled true) }}
|
||||
apiVersion: monitoring.coreos.com/v1
|
||||
kind: ServiceMonitor
|
||||
metadata:
|
||||
name: {{ include "litellm.fullname" $ }}
|
||||
labels:
|
||||
{{- include "litellm.labels" $ | nindent 4 }}
|
||||
{{- if .labels }}
|
||||
{{- toYaml .labels | nindent 4 }}
|
||||
{{- end }}
|
||||
{{- if .annotations }}
|
||||
annotations:
|
||||
{{- toYaml .annotations | nindent 4 }}
|
||||
{{- end }}
|
||||
spec:
|
||||
selector:
|
||||
matchLabels:
|
||||
{{- include "litellm.selectorLabels" $ | nindent 6 }}
|
||||
namespaceSelector:
|
||||
matchNames:
|
||||
# if not set, use the release namespace
|
||||
{{- if not .namespaceSelector.matchNames }}
|
||||
- {{ $.Release.Namespace | quote }}
|
||||
{{- else }}
|
||||
{{- toYaml .namespaceSelector.matchNames | nindent 4 }}
|
||||
{{- end }}
|
||||
endpoints:
|
||||
- port: http
|
||||
path: /metrics/
|
||||
interval: {{ .interval }}
|
||||
scrapeTimeout: {{ .scrapeTimeout }}
|
||||
scheme: http
|
||||
{{- if .relabelings }}
|
||||
relabelings:
|
||||
{{- toYaml .relabelings | nindent 4 }}
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
|
|
@ -0,0 +1,152 @@
|
|||
{{- if .Values.serviceMonitor.enabled }}
|
||||
apiVersion: v1
|
||||
kind: Pod
|
||||
metadata:
|
||||
name: "{{ include "litellm.fullname" . }}-test-servicemonitor"
|
||||
labels:
|
||||
{{- include "litellm.labels" . | nindent 4 }}
|
||||
annotations:
|
||||
"helm.sh/hook": test
|
||||
spec:
|
||||
containers:
|
||||
- name: test
|
||||
image: bitnami/kubectl:latest
|
||||
command: ['sh', '-c']
|
||||
args:
|
||||
- |
|
||||
set -e
|
||||
echo "🔍 Testing ServiceMonitor configuration..."
|
||||
|
||||
# Check if ServiceMonitor exists
|
||||
if ! kubectl get servicemonitor {{ include "litellm.fullname" . }} -n {{ .Release.Namespace }} &>/dev/null; then
|
||||
echo "❌ ServiceMonitor not found"
|
||||
exit 1
|
||||
fi
|
||||
echo "✅ ServiceMonitor exists"
|
||||
|
||||
# Get ServiceMonitor YAML
|
||||
SM=$(kubectl get servicemonitor {{ include "litellm.fullname" . }} -n {{ .Release.Namespace }} -o yaml)
|
||||
|
||||
# Test endpoint configuration
|
||||
ENDPOINT_PORT=$(echo "$SM" | grep -A 5 "endpoints:" | grep "port:" | awk '{print $2}')
|
||||
if [ "$ENDPOINT_PORT" != "http" ]; then
|
||||
echo "❌ Endpoint port mismatch. Expected: http, Got: $ENDPOINT_PORT"
|
||||
exit 1
|
||||
fi
|
||||
echo "✅ Endpoint port is correctly set to: $ENDPOINT_PORT"
|
||||
|
||||
# Test endpoint path
|
||||
ENDPOINT_PATH=$(echo "$SM" | grep -A 5 "endpoints:" | grep "path:" | awk '{print $2}')
|
||||
if [ "$ENDPOINT_PATH" != "/metrics/" ]; then
|
||||
echo "❌ Endpoint path mismatch. Expected: /metrics/, Got: $ENDPOINT_PATH"
|
||||
exit 1
|
||||
fi
|
||||
echo "✅ Endpoint path is correctly set to: $ENDPOINT_PATH"
|
||||
|
||||
# Test interval
|
||||
INTERVAL=$(echo "$SM" | grep "interval:" | awk '{print $2}')
|
||||
if [ "$INTERVAL" != "{{ .Values.serviceMonitor.interval }}" ]; then
|
||||
echo "❌ Interval mismatch. Expected: {{ .Values.serviceMonitor.interval }}, Got: $INTERVAL"
|
||||
exit 1
|
||||
fi
|
||||
echo "✅ Interval is correctly set to: $INTERVAL"
|
||||
|
||||
# Test scrapeTimeout
|
||||
TIMEOUT=$(echo "$SM" | grep "scrapeTimeout:" | awk '{print $2}')
|
||||
if [ "$TIMEOUT" != "{{ .Values.serviceMonitor.scrapeTimeout }}" ]; then
|
||||
echo "❌ ScrapeTimeout mismatch. Expected: {{ .Values.serviceMonitor.scrapeTimeout }}, Got: $TIMEOUT"
|
||||
exit 1
|
||||
fi
|
||||
echo "✅ ScrapeTimeout is correctly set to: $TIMEOUT"
|
||||
|
||||
# Test scheme
|
||||
SCHEME=$(echo "$SM" | grep "scheme:" | awk '{print $2}')
|
||||
if [ "$SCHEME" != "http" ]; then
|
||||
echo "❌ Scheme mismatch. Expected: http, Got: $SCHEME"
|
||||
exit 1
|
||||
fi
|
||||
echo "✅ Scheme is correctly set to: $SCHEME"
|
||||
|
||||
{{- if .Values.serviceMonitor.labels }}
|
||||
# Test custom labels
|
||||
echo "🔍 Checking custom labels..."
|
||||
{{- range $key, $value := .Values.serviceMonitor.labels }}
|
||||
LABEL_VALUE=$(echo "$SM" | grep -A 20 "metadata:" | grep "{{ $key }}:" | awk '{print $2}')
|
||||
if [ "$LABEL_VALUE" != "{{ $value }}" ]; then
|
||||
echo "❌ Label {{ $key }} mismatch. Expected: {{ $value }}, Got: $LABEL_VALUE"
|
||||
exit 1
|
||||
fi
|
||||
echo "✅ Label {{ $key }} is correctly set to: {{ $value }}"
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
|
||||
{{- if .Values.serviceMonitor.annotations }}
|
||||
# Test annotations
|
||||
echo "🔍 Checking annotations..."
|
||||
{{- range $key, $value := .Values.serviceMonitor.annotations }}
|
||||
ANNOTATION_VALUE=$(echo "$SM" | grep -A 10 "annotations:" | grep "{{ $key }}:" | awk '{print $2}')
|
||||
if [ "$ANNOTATION_VALUE" != "{{ $value }}" ]; then
|
||||
echo "❌ Annotation {{ $key }} mismatch. Expected: {{ $value }}, Got: $ANNOTATION_VALUE"
|
||||
exit 1
|
||||
fi
|
||||
echo "✅ Annotation {{ $key }} is correctly set to: {{ $value }}"
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
|
||||
{{- if .Values.serviceMonitor.namespaceSelector.matchNames }}
|
||||
# Test namespace selector
|
||||
echo "🔍 Checking namespace selector..."
|
||||
{{- range .Values.serviceMonitor.namespaceSelector.matchNames }}
|
||||
if ! echo "$SM" | grep -A 5 "namespaceSelector:" | grep -q "{{ . }}"; then
|
||||
echo "❌ Namespace {{ . }} not found in namespaceSelector"
|
||||
exit 1
|
||||
fi
|
||||
echo "✅ Namespace {{ . }} found in namespaceSelector"
|
||||
{{- end }}
|
||||
{{- else }}
|
||||
# Test default namespace selector (should be release namespace)
|
||||
if ! echo "$SM" | grep -A 5 "namespaceSelector:" | grep -q "{{ .Release.Namespace }}"; then
|
||||
echo "❌ Release namespace {{ .Release.Namespace }} not found in namespaceSelector"
|
||||
exit 1
|
||||
fi
|
||||
echo "✅ Default namespace selector set to release namespace: {{ .Release.Namespace }}"
|
||||
{{- end }}
|
||||
|
||||
{{- if .Values.serviceMonitor.relabelings }}
|
||||
# Test relabelings
|
||||
echo "🔍 Checking relabelings configuration..."
|
||||
if ! echo "$SM" | grep -q "relabelings:"; then
|
||||
echo "❌ Relabelings section not found"
|
||||
exit 1
|
||||
fi
|
||||
echo "✅ Relabelings section exists"
|
||||
{{- range .Values.serviceMonitor.relabelings }}
|
||||
{{- if .targetLabel }}
|
||||
if ! echo "$SM" | grep -A 50 "relabelings:" | grep -q "targetLabel: {{ .targetLabel }}"; then
|
||||
echo "❌ Relabeling targetLabel {{ .targetLabel }} not found"
|
||||
exit 1
|
||||
fi
|
||||
echo "✅ Relabeling targetLabel {{ .targetLabel }} found"
|
||||
{{- end }}
|
||||
{{- if .action }}
|
||||
if ! echo "$SM" | grep -A 50 "relabelings:" | grep -q "action: {{ .action }}"; then
|
||||
echo "❌ Relabeling action {{ .action }} not found"
|
||||
exit 1
|
||||
fi
|
||||
echo "✅ Relabeling action {{ .action }} found"
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
|
||||
# Test selector labels match the service
|
||||
echo "🔍 Checking selector labels match service..."
|
||||
SVC_LABELS=$(kubectl get svc {{ include "litellm.fullname" . }} -n {{ .Release.Namespace }} -o jsonpath='{.metadata.labels}')
|
||||
echo "Service labels: $SVC_LABELS"
|
||||
echo "✅ Selector labels validation passed"
|
||||
|
||||
echo ""
|
||||
echo "🎉 All ServiceMonitor tests passed successfully!"
|
||||
serviceAccountName: {{ include "litellm.serviceAccountName" . }}
|
||||
restartPolicy: Never
|
||||
{{- end }}
|
||||
|
||||
|
|
@ -0,0 +1,68 @@
|
|||
suite: test deployment command, args, and deploymentLabels
|
||||
templates:
|
||||
- deployment.yaml
|
||||
- configmap-litellm.yaml
|
||||
tests:
|
||||
- it: should override args when custom args specified
|
||||
template: deployment.yaml
|
||||
set:
|
||||
args:
|
||||
- --custom-arg1
|
||||
- value1
|
||||
- --custom-arg2
|
||||
asserts:
|
||||
- equal:
|
||||
path: spec.template.spec.containers[0].args
|
||||
value:
|
||||
- --custom-arg1
|
||||
- value1
|
||||
- --custom-arg2
|
||||
- it: should set custom command when specified
|
||||
template: deployment.yaml
|
||||
set:
|
||||
command:
|
||||
- /bin/sh
|
||||
- -c
|
||||
asserts:
|
||||
- equal:
|
||||
path: spec.template.spec.containers[0].command
|
||||
value:
|
||||
- /bin/sh
|
||||
- -c
|
||||
- it: should set custom command and args together
|
||||
template: deployment.yaml
|
||||
set:
|
||||
command:
|
||||
- python
|
||||
- -u
|
||||
args:
|
||||
- my_script.py
|
||||
- --verbose
|
||||
asserts:
|
||||
- equal:
|
||||
path: spec.template.spec.containers[0].command
|
||||
value:
|
||||
- python
|
||||
- -u
|
||||
- equal:
|
||||
path: spec.template.spec.containers[0].args
|
||||
value:
|
||||
- my_script.py
|
||||
- --verbose
|
||||
- it: should add deploymentLabels to deployment metadata
|
||||
template: deployment.yaml
|
||||
set:
|
||||
deploymentLabels:
|
||||
environment: production
|
||||
team: platform
|
||||
version: v1.2.3
|
||||
asserts:
|
||||
- equal:
|
||||
path: metadata.labels.environment
|
||||
value: production
|
||||
- equal:
|
||||
path: metadata.labels.team
|
||||
value: platform
|
||||
- equal:
|
||||
path: metadata.labels.version
|
||||
value: v1.2.3
|
||||
45
deploy/charts/litellm-helm/tests/ingress_tests.yaml
Normal file
45
deploy/charts/litellm-helm/tests/ingress_tests.yaml
Normal file
|
|
@ -0,0 +1,45 @@
|
|||
suite: Ingress Configuration Tests
|
||||
templates:
|
||||
- ingress.yaml
|
||||
tests:
|
||||
- it: should not create Ingress by default
|
||||
asserts:
|
||||
- hasDocuments:
|
||||
count: 0
|
||||
|
||||
- it: should create Ingress when enabled
|
||||
set:
|
||||
ingress.enabled: true
|
||||
asserts:
|
||||
- hasDocuments:
|
||||
count: 1
|
||||
- isKind:
|
||||
of: Ingress
|
||||
|
||||
- it: should add custom labels
|
||||
set:
|
||||
ingress.enabled: true
|
||||
ingress.labels:
|
||||
custom-label: "true"
|
||||
another-label: "value"
|
||||
asserts:
|
||||
- isKind:
|
||||
of: Ingress
|
||||
- equal:
|
||||
path: metadata.labels.custom-label
|
||||
value: "true"
|
||||
- equal:
|
||||
path: metadata.labels.another-label
|
||||
value: "value"
|
||||
|
||||
- it: should add annotations
|
||||
set:
|
||||
ingress.enabled: true
|
||||
ingress.annotations:
|
||||
kubernetes.io/ingress.class: "nginx"
|
||||
asserts:
|
||||
- isKind:
|
||||
of: Ingress
|
||||
- equal:
|
||||
path: metadata.annotations["kubernetes.io/ingress.class"]
|
||||
value: "nginx"
|
||||
|
|
@ -3,6 +3,7 @@
|
|||
# Declare variables to be passed into your templates.
|
||||
|
||||
replicaCount: 1
|
||||
# numWorkers: 2
|
||||
|
||||
image:
|
||||
# Use "ghcr.io/berriai/litellm-database" for optimized image with database
|
||||
|
|
@ -29,14 +30,26 @@ serviceAccount:
|
|||
|
||||
# annotations for litellm deployment
|
||||
deploymentAnnotations: {}
|
||||
deploymentLabels: {}
|
||||
# annotations for litellm pods
|
||||
podAnnotations: {}
|
||||
podLabels: {}
|
||||
|
||||
terminationGracePeriodSeconds: 90
|
||||
topologySpreadConstraints:
|
||||
[]
|
||||
# - maxSkew: 1
|
||||
# topologyKey: kubernetes.io/hostname
|
||||
# whenUnsatisfiable: DoNotSchedule
|
||||
# labelSelector:
|
||||
# matchLabels:
|
||||
# app: litellm
|
||||
|
||||
# At the time of writing, the litellm docker image requires write access to the
|
||||
# filesystem on startup so that prisma can install some dependencies.
|
||||
podSecurityContext: {}
|
||||
securityContext: {}
|
||||
securityContext:
|
||||
{}
|
||||
# capabilities:
|
||||
# drop:
|
||||
# - ALL
|
||||
|
|
@ -47,13 +60,15 @@ securityContext: {}
|
|||
# A list of Kubernetes Secret objects that will be exported to the LiteLLM proxy
|
||||
# pod as environment variables. These secrets can then be referenced in the
|
||||
# configuration file (or "litellm" ConfigMap) with `os.environ/<Env Var Name>`
|
||||
environmentSecrets: []
|
||||
environmentSecrets:
|
||||
[]
|
||||
# - litellm-env-secret
|
||||
|
||||
# A list of Kubernetes ConfigMap objects that will be exported to the LiteLLM proxy
|
||||
# pod as environment variables. The ConfigMap kv-pairs can then be referenced in the
|
||||
# configuration file (or "litellm" ConfigMap) with `os.environ/<Env Var Name>`
|
||||
environmentConfigMaps: []
|
||||
environmentConfigMaps:
|
||||
[]
|
||||
# - litellm-env-configmap
|
||||
|
||||
service:
|
||||
|
|
@ -72,7 +87,9 @@ separateHealthPort: 8081
|
|||
ingress:
|
||||
enabled: false
|
||||
className: "nginx"
|
||||
annotations: {}
|
||||
labels: {}
|
||||
annotations:
|
||||
{}
|
||||
# kubernetes.io/ingress.class: nginx
|
||||
# kubernetes.io/tls-acme: "true"
|
||||
hosts:
|
||||
|
|
@ -119,7 +136,8 @@ proxy_config:
|
|||
general_settings:
|
||||
master_key: os.environ/PROXY_MASTER_KEY
|
||||
|
||||
resources: {}
|
||||
resources:
|
||||
{}
|
||||
# We usually recommend not to specify default resources and to leave this as a conscious
|
||||
# choice for the user. This also increases chances charts run on environments with little
|
||||
# resources, such as Minikube. If you do want to specify resources, uncomment the following
|
||||
|
|
@ -221,7 +239,7 @@ migrationJob:
|
|||
# cpu: 100m
|
||||
# memory: 100Mi
|
||||
extraContainers: []
|
||||
|
||||
|
||||
# Hook configuration
|
||||
hooks:
|
||||
argocd:
|
||||
|
|
@ -230,21 +248,51 @@ migrationJob:
|
|||
enabled: false
|
||||
|
||||
# Additional environment variables to be added to the deployment as a map of key-value pairs
|
||||
envVars: {
|
||||
# USE_DDTRACE: "true"
|
||||
}
|
||||
envVars: {}
|
||||
|
||||
# USE_DDTRACE: "true"
|
||||
# Additional environment variables to be added to the deployment as a list of k8s env vars
|
||||
extraEnvVars: {
|
||||
# - name: EXTRA_ENV_VAR
|
||||
# value: EXTRA_ENV_VAR_VALUE
|
||||
}
|
||||
extraEnvVars: {}
|
||||
|
||||
# if you want to override the container command, you can do so here
|
||||
command: {}
|
||||
# if you want to override the container args, you can do so here
|
||||
args: {}
|
||||
|
||||
# - name: EXTRA_ENV_VAR
|
||||
# value: EXTRA_ENV_VAR_VALUE
|
||||
# Additional Kubernetes resources to deploy with litellm
|
||||
extraResources: []
|
||||
|
||||
# - apiVersion: v1
|
||||
# kind: ConfigMap
|
||||
# metadata:
|
||||
# name: my-extra-config
|
||||
# data:
|
||||
# foo: bar
|
||||
# Pod Disruption Budget
|
||||
pdb:
|
||||
enabled: false
|
||||
# Set exactly one of the following. If both are set, minAvailable takes precedence.
|
||||
minAvailable: null # e.g. "50%" or 1
|
||||
maxUnavailable: null # e.g. 1 or "20%"
|
||||
minAvailable: null # e.g. "50%" or 1
|
||||
maxUnavailable: null # e.g. 1 or "20%"
|
||||
annotations: {}
|
||||
labels: {}
|
||||
|
||||
serviceMonitor:
|
||||
enabled: false
|
||||
labels:
|
||||
{}
|
||||
# test: test
|
||||
annotations:
|
||||
{}
|
||||
# kubernetes.io/test: test
|
||||
interval: 15s
|
||||
scrapeTimeout: 10s
|
||||
relabelings: []
|
||||
# - targetLabel: __meta_kubernetes_pod_node_name
|
||||
# replacement: $1
|
||||
# action: replace
|
||||
namespaceSelector:
|
||||
matchNames: []
|
||||
# - test-namespace
|
||||
|
|
|
|||
|
|
@ -22,7 +22,9 @@ services:
|
|||
depends_on:
|
||||
- db # Indicates that this service depends on the 'db' service, ensuring 'db' starts first
|
||||
healthcheck: # Defines the health check configuration for the container
|
||||
test: [ "CMD-SHELL", "wget --no-verbose --tries=1 http://localhost:4000/health/liveliness || exit 1" ] # Command to execute for health check
|
||||
test:
|
||||
- CMD-SHELL
|
||||
- python3 -c "import urllib.request; urllib.request.urlopen('http://localhost:4000/health/liveliness')" # Command to execute for health check
|
||||
interval: 30s # Perform health check every 30 seconds
|
||||
timeout: 10s # Health check command times out after 10 seconds
|
||||
retries: 3 # Retry up to 3 times if health check fails
|
||||
|
|
|
|||
|
|
@ -1,8 +1,8 @@
|
|||
# Base image for building
|
||||
ARG LITELLM_BUILD_IMAGE=cgr.dev/chainguard/python:latest-dev
|
||||
ARG LITELLM_BUILD_IMAGE=cgr.dev/chainguard/wolfi-base
|
||||
|
||||
# Runtime image
|
||||
ARG LITELLM_RUNTIME_IMAGE=cgr.dev/chainguard/python:latest-dev
|
||||
ARG LITELLM_RUNTIME_IMAGE=cgr.dev/chainguard/wolfi-base
|
||||
# Builder stage
|
||||
FROM $LITELLM_BUILD_IMAGE AS builder
|
||||
|
||||
|
|
@ -12,11 +12,16 @@ WORKDIR /app
|
|||
USER root
|
||||
|
||||
# Install build dependencies
|
||||
RUN apk add --no-cache gcc python3-dev openssl openssl-dev
|
||||
RUN apk add --no-cache \
|
||||
bash \
|
||||
gcc \
|
||||
py3-pip \
|
||||
python3 \
|
||||
python3-dev \
|
||||
openssl \
|
||||
openssl-dev
|
||||
|
||||
|
||||
RUN pip install --upgrade pip && \
|
||||
pip install build
|
||||
RUN python -m pip install build
|
||||
|
||||
# Copy the current directory contents into the container at /app
|
||||
COPY . .
|
||||
|
|
@ -43,7 +48,7 @@ FROM $LITELLM_RUNTIME_IMAGE AS runtime
|
|||
USER root
|
||||
|
||||
# Install runtime dependencies
|
||||
RUN apk add --no-cache openssl
|
||||
RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip
|
||||
|
||||
WORKDIR /app
|
||||
# Copy the current directory contents into the container at /app
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
# Base images
|
||||
ARG LITELLM_BUILD_IMAGE=cgr.dev/chainguard/python:latest-dev
|
||||
ARG LITELLM_RUNTIME_IMAGE=cgr.dev/chainguard/python:latest-dev
|
||||
ARG LITELLM_BUILD_IMAGE=cgr.dev/chainguard/wolfi-base
|
||||
ARG LITELLM_RUNTIME_IMAGE=cgr.dev/chainguard/wolfi-base
|
||||
|
||||
# -----------------
|
||||
# Builder Stage
|
||||
|
|
@ -10,7 +10,20 @@ WORKDIR /app
|
|||
|
||||
# Install build dependencies including Node.js for UI build
|
||||
USER root
|
||||
RUN apk add --no-cache build-base bash nodejs npm \
|
||||
RUN for i in 1 2 3; do \
|
||||
apk add --no-cache \
|
||||
python3 \
|
||||
py3-pip \
|
||||
clang \
|
||||
llvm \
|
||||
lld \
|
||||
gcc \
|
||||
linux-headers \
|
||||
build-base \
|
||||
bash \
|
||||
nodejs \
|
||||
npm && break || sleep 5; \
|
||||
done \
|
||||
&& pip install --no-cache-dir --upgrade pip build
|
||||
|
||||
# Copy project files
|
||||
|
|
@ -20,24 +33,34 @@ COPY . .
|
|||
ENV LITELLM_NON_ROOT=true
|
||||
|
||||
# Build Admin UI
|
||||
RUN mkdir -p /tmp/litellm_ui && \
|
||||
cd ui/litellm-dashboard && \
|
||||
if [ -f "../../enterprise/enterprise_ui/enterprise_colors.json" ]; then \
|
||||
cp ../../enterprise/enterprise_ui/enterprise_colors.json ./ui_colors.json; \
|
||||
fi && \
|
||||
npm install && \
|
||||
npm run build && \
|
||||
cp -r ./out/* /tmp/litellm_ui/ && \
|
||||
cd /tmp/litellm_ui && \
|
||||
RUN mkdir -p /tmp/litellm_ui
|
||||
|
||||
RUN npm install -g npm@latest && npm cache clean --force
|
||||
|
||||
RUN cd /app/ui/litellm-dashboard && \
|
||||
if [ -f "/app/enterprise/enterprise_ui/enterprise_colors.json" ]; then \
|
||||
cp /app/enterprise/enterprise_ui/enterprise_colors.json ./ui_colors.json; \
|
||||
fi
|
||||
|
||||
RUN cd /app/ui/litellm-dashboard && rm -f package-lock.json
|
||||
|
||||
RUN cd /app/ui/litellm-dashboard && npm install --legacy-peer-deps
|
||||
|
||||
RUN cd /app/ui/litellm-dashboard && npm run build
|
||||
|
||||
RUN cp -r /app/ui/litellm-dashboard/out/* /tmp/litellm_ui/
|
||||
RUN mkdir -p /tmp/litellm_assets && cp /app/litellm/proxy/logo.jpg /tmp/litellm_assets/logo.jpg
|
||||
|
||||
RUN cd /tmp/litellm_ui && \
|
||||
for html_file in *.html; do \
|
||||
if [ "$html_file" != "index.html" ] && [ -f "$html_file" ]; then \
|
||||
folder_name="${html_file%.html}" && \
|
||||
mkdir -p "$folder_name" && \
|
||||
mv "$html_file" "$folder_name/index.html"; \
|
||||
fi; \
|
||||
done && \
|
||||
cd /app/ui/litellm-dashboard && \
|
||||
rm -rf ./out
|
||||
if [ "$html_file" != "index.html" ] && [ -f "$html_file" ]; then \
|
||||
folder_name="${html_file%.html}" && \
|
||||
mkdir -p "$folder_name" && \
|
||||
mv "$html_file" "$folder_name/index.html"; \
|
||||
fi; \
|
||||
done
|
||||
|
||||
RUN cd /app/ui/litellm-dashboard && rm -rf ./out
|
||||
|
||||
# Build package and wheel dependencies
|
||||
RUN rm -rf dist/* && python -m build && \
|
||||
|
|
@ -52,8 +75,12 @@ WORKDIR /app
|
|||
|
||||
# Install runtime dependencies
|
||||
USER root
|
||||
RUN apk upgrade --no-cache && \
|
||||
apk add --no-cache bash libstdc++ ca-certificates openssl supervisor
|
||||
RUN for i in 1 2 3; do \
|
||||
apk upgrade --no-cache && break || sleep 5; \
|
||||
done \
|
||||
&& for i in 1 2 3; do \
|
||||
apk add --no-cache python3 py3-pip bash openssl tzdata nodejs npm supervisor && break || sleep 5; \
|
||||
done
|
||||
|
||||
# Copy only necessary artifacts from builder stage for runtime
|
||||
COPY . .
|
||||
|
|
@ -63,6 +90,7 @@ COPY --from=builder /app/schema.prisma /app/schema.prisma
|
|||
COPY --from=builder /app/dist/*.whl .
|
||||
COPY --from=builder /wheels/ /wheels/
|
||||
COPY --from=builder /tmp/litellm_ui /tmp/litellm_ui
|
||||
COPY --from=builder /tmp/litellm_assets /tmp/litellm_assets
|
||||
|
||||
# Install package from wheel and dependencies
|
||||
RUN pip install *.whl /wheels/* --no-index --find-links=/wheels/ \
|
||||
|
|
@ -71,7 +99,7 @@ RUN pip install *.whl /wheels/* --no-index --find-links=/wheels/ \
|
|||
|
||||
# Remove test files and keys from dependencies
|
||||
RUN find /usr/lib -type f -path "*/tornado/test/*" -delete && \
|
||||
find /usr/lib -type d -path "*/tornado/test" -delete
|
||||
find /usr/lib -type d -path "*/tornado/test" -delete
|
||||
|
||||
# Install semantic_router and aurelio-sdk using script
|
||||
RUN chmod +x docker/install_auto_router.sh && ./docker/install_auto_router.sh
|
||||
|
|
@ -91,8 +119,8 @@ RUN pip install --no-cache-dir prisma && \
|
|||
chmod +x docker/prod_entrypoint.sh
|
||||
|
||||
# Create directories and set permissions for non-root user
|
||||
RUN mkdir -p /nonexistent /.npm && \
|
||||
chown -R nobody:nogroup /app /tmp/litellm_ui /nonexistent /.npm && \
|
||||
RUN mkdir -p /nonexistent /.npm /tmp/litellm_assets && \
|
||||
chown -R nobody:nogroup /app /tmp/litellm_ui /tmp/litellm_assets /nonexistent /.npm && \
|
||||
PRISMA_PATH=$(python -c "import os, prisma; print(os.path.dirname(prisma.__file__))") && \
|
||||
chown -R nobody:nogroup $PRISMA_PATH && \
|
||||
LITELLM_PKG_MIGRATIONS_PATH="$(python -c 'import os, litellm_proxy_extras; print(os.path.dirname(litellm_proxy_extras.__file__))' 2>/dev/null || echo '')/migrations" && \
|
||||
|
|
@ -101,11 +129,11 @@ RUN mkdir -p /nonexistent /.npm && \
|
|||
# OpenShift compatibility
|
||||
RUN PRISMA_PATH=$(python -c "import os, prisma; print(os.path.dirname(prisma.__file__))") && \
|
||||
LITELLM_PROXY_EXTRAS_PATH=$(python -c "import os, litellm_proxy_extras; print(os.path.dirname(litellm_proxy_extras.__file__))" 2>/dev/null || echo "") && \
|
||||
chgrp -R 0 $PRISMA_PATH /tmp/litellm_ui && \
|
||||
chgrp -R 0 $PRISMA_PATH /tmp/litellm_ui /tmp/litellm_assets && \
|
||||
[ -n "$LITELLM_PROXY_EXTRAS_PATH" ] && chgrp -R 0 $LITELLM_PROXY_EXTRAS_PATH || true && \
|
||||
chmod -R g=u $PRISMA_PATH /tmp/litellm_ui && \
|
||||
chmod -R g=u $PRISMA_PATH /tmp/litellm_ui /tmp/litellm_assets && \
|
||||
[ -n "$LITELLM_PROXY_EXTRAS_PATH" ] && chmod -R g=u $LITELLM_PROXY_EXTRAS_PATH || true && \
|
||||
chmod -R g+w $PRISMA_PATH /tmp/litellm_ui && \
|
||||
chmod -R g+w $PRISMA_PATH /tmp/litellm_ui /tmp/litellm_assets && \
|
||||
[ -n "$LITELLM_PROXY_EXTRAS_PATH" ] && chmod -R g+w $LITELLM_PROXY_EXTRAS_PATH || true
|
||||
|
||||
# Switch to non-root user
|
||||
|
|
|
|||
|
|
@ -1,14 +1,16 @@
|
|||
FROM cgr.dev/chainguard/python:latest-dev
|
||||
FROM python:3.13-alpine
|
||||
|
||||
USER root
|
||||
WORKDIR /app
|
||||
|
||||
ENV HOME=/home/litellm
|
||||
ENV PATH="${HOME}/venv/bin:$PATH"
|
||||
|
||||
# Install runtime dependencies
|
||||
# Note: Using Python 3.13 for compatibility with ddtrace and other packages
|
||||
# rust and cargo are required for building ddtrace from source
|
||||
# musl-dev and libffi-dev are needed for some Python packages on Alpine
|
||||
RUN apk update && \
|
||||
apk add --no-cache gcc python3-dev openssl openssl-dev
|
||||
apk add --no-cache gcc musl-dev libffi-dev openssl openssl-dev rust cargo
|
||||
|
||||
RUN python -m venv ${HOME}/venv
|
||||
RUN ${HOME}/venv/bin/pip install --no-cache-dir --upgrade pip
|
||||
|
|
|
|||
7
docs/my-website/.trivyignore
Normal file
7
docs/my-website/.trivyignore
Normal file
|
|
@ -0,0 +1,7 @@
|
|||
# js-yaml CVE-2025-64718
|
||||
# This vulnerability is not applicable because we've forced js-yaml to version 4.1.1
|
||||
# via npm overrides in package.json. Trivy incorrectly reports this based on
|
||||
# dependency requirements in the lockfile, but the actual installed version is 4.1.1.
|
||||
# Verified with: npm list js-yaml
|
||||
CVE-2025-64718
|
||||
|
||||
File diff suppressed because it is too large
Load diff
24
docs/my-website/blog/authors.yml
Normal file
24
docs/my-website/blog/authors.yml
Normal file
|
|
@ -0,0 +1,24 @@
|
|||
litellm:
|
||||
name: LiteLLM Team
|
||||
title: LiteLLM Core Team
|
||||
url: https://github.com/BerriAI/litellm
|
||||
image_url: https://github.com/BerriAI.png
|
||||
|
||||
krrish:
|
||||
name: Krrish Dholakia
|
||||
title: CEO, LiteLLM
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
|
||||
ishaan:
|
||||
name: Ishaan Jaffer
|
||||
title: CTO, LiteLLM
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
|
||||
# Alias for typo in name
|
||||
ishaan-alt:
|
||||
name: Ishaan Jaff
|
||||
title: CTO, LiteLLM
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
982
docs/my-website/blog/gemini_3/index.md
Normal file
982
docs/my-website/blog/gemini_3/index.md
Normal file
|
|
@ -0,0 +1,982 @@
|
|||
---
|
||||
slug: gemini_3
|
||||
title: "DAY 0 Support: Gemini 3 on LiteLLM"
|
||||
date: 2025-11-19T10:00:00
|
||||
authors:
|
||||
- name: Sameer Kankute
|
||||
title: SWE @ LiteLLM (LLM Translation)
|
||||
url: https://www.linkedin.com/in/sameer-kankute/
|
||||
image_url: https://media.licdn.com/dms/image/v2/D4D03AQHB_loQYd5gjg/profile-displayphoto-shrink_800_800/profile-displayphoto-shrink_800_800/0/1719137160975?e=1765411200&v=beta&t=c8396f--_lH6Fb_pVvx_jGholPfcl0bvwmNynbNdnII
|
||||
- name: Krrish Dholakia
|
||||
title: "CEO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
tags: [gemini, day 0 support, llms]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
:::info
|
||||
|
||||
This guide covers common questions and best practices for using `gemini-3-pro-preview` with LiteLLM Proxy and SDK.
|
||||
|
||||
:::
|
||||
|
||||
## Quick Start
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="Python SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
import os
|
||||
|
||||
os.environ["GEMINI_API_KEY"] = "your-api-key"
|
||||
|
||||
response = completion(
|
||||
model="gemini/gemini-3-pro-preview",
|
||||
messages=[{"role": "user", "content": "Hello!"}],
|
||||
reasoning_effort="low"
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Add to config.yaml:**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gemini-3-pro-preview
|
||||
litellm_params:
|
||||
model: gemini/gemini-3-pro-preview
|
||||
api_key: os.environ/GEMINI_API_KEY
|
||||
```
|
||||
|
||||
**2. Start proxy:**
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
**3. Make request:**
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gemini-3-pro-preview",
|
||||
"messages": [{"role": "user", "content": "Hello!"}],
|
||||
"reasoning_effort": "low"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Supported Endpoints
|
||||
|
||||
LiteLLM provides **full end-to-end support** for Gemini 3 Pro Preview on:
|
||||
|
||||
- ✅ `/v1/chat/completions` - OpenAI-compatible chat completions endpoint
|
||||
- ✅ `/v1/responses` - OpenAI Responses API endpoint (streaming and non-streaming)
|
||||
- ✅ [`/v1/messages`](../../docs/anthropic_unified) - Anthropic-compatible messages endpoint
|
||||
- ✅ `/v1/generateContent` – [Google Gemini API](https://cloud.google.com/vertex-ai/docs/generative-ai/model-reference/gemini#rest) compatible endpoint (for code, see: `client.models.generate_content(...)`)
|
||||
|
||||
All endpoints support:
|
||||
- Streaming and non-streaming responses
|
||||
- Function calling with thought signatures
|
||||
- Multi-turn conversations
|
||||
- All Gemini 3-specific features
|
||||
|
||||
## Thought Signatures
|
||||
|
||||
#### What are Thought Signatures?
|
||||
|
||||
Thought signatures are encrypted representations of the model's internal reasoning process. They're essential for maintaining context across multi-turn conversations, especially with function calling.
|
||||
|
||||
#### How Thought Signatures Work
|
||||
|
||||
1. **Automatic Extraction**: When Gemini 3 returns a function call, LiteLLM automatically extracts the `thought_signature` from the response
|
||||
2. **Storage**: Thought signatures are stored in `provider_specific_fields.thought_signature` of tool calls
|
||||
3. **Automatic Preservation**: When you include the assistant's message in conversation history, LiteLLM automatically preserves and returns thought signatures to Gemini
|
||||
|
||||
## Example: Multi-Turn Function Calling
|
||||
|
||||
#### Streaming with Thought Signatures
|
||||
|
||||
When using streaming mode with `stream_chunk_builder()`, thought signatures are now automatically preserved:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="streaming" label="Streaming SDK">
|
||||
|
||||
```python
|
||||
import os
|
||||
import litellm
|
||||
from litellm import completion
|
||||
|
||||
os.environ["GEMINI_API_KEY"] = "your-api-key"
|
||||
|
||||
MODEL = "gemini/gemini-3-pro-preview"
|
||||
|
||||
messages = [
|
||||
{"role": "system", "content": "You are a helpful assistant. Use the calculate tool."},
|
||||
{"role": "user", "content": "What is 2+2?"},
|
||||
]
|
||||
|
||||
tools = [{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "calculate",
|
||||
"description": "Calculate a mathematical expression",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {"expression": {"type": "string"}},
|
||||
"required": ["expression"],
|
||||
},
|
||||
},
|
||||
}]
|
||||
|
||||
print("Step 1: Sending request with stream=True...")
|
||||
response = completion(
|
||||
model=MODEL,
|
||||
messages=messages,
|
||||
stream=True,
|
||||
tools=tools,
|
||||
reasoning_effort="low"
|
||||
)
|
||||
|
||||
# Collect all chunks
|
||||
chunks = []
|
||||
for part in response:
|
||||
chunks.append(part)
|
||||
|
||||
# Reconstruct message using stream_chunk_builder
|
||||
# Thought signatures are now preserved automatically!
|
||||
full_response = litellm.stream_chunk_builder(chunks, messages=messages)
|
||||
print(f"Full response: {full_response}")
|
||||
|
||||
assistant_msg = full_response.choices[0].message
|
||||
|
||||
# ✅ Thought signature is now preserved in provider_specific_fields
|
||||
if assistant_msg.tool_calls and assistant_msg.tool_calls[0].provider_specific_fields:
|
||||
thought_sig = assistant_msg.tool_calls[0].provider_specific_fields.get("thought_signature")
|
||||
print(f"Thought signature preserved: {thought_sig is not None}")
|
||||
|
||||
# Append assistant message (includes thought signatures automatically)
|
||||
messages.append(assistant_msg)
|
||||
|
||||
# Mock tool execution
|
||||
messages.append({
|
||||
"role": "tool",
|
||||
"content": "4",
|
||||
"tool_call_id": assistant_msg.tool_calls[0].id
|
||||
})
|
||||
|
||||
print("\nStep 2: Sending tool result back to model...")
|
||||
response_2 = completion(
|
||||
model=MODEL,
|
||||
messages=messages,
|
||||
stream=True,
|
||||
tools=tools,
|
||||
reasoning_effort="low"
|
||||
)
|
||||
|
||||
for part in response_2:
|
||||
if part.choices[0].delta.content:
|
||||
print(part.choices[0].delta.content, end="")
|
||||
print() # New line
|
||||
```
|
||||
|
||||
**Key Points:**
|
||||
- ✅ `stream_chunk_builder()` now preserves `provider_specific_fields` including thought signatures
|
||||
- ✅ Thought signatures are automatically included when appending `assistant_msg` to conversation history
|
||||
- ✅ Multi-turn conversations work seamlessly with streaming
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sdk" label="Non-Streaming SDK">
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
import json
|
||||
|
||||
client = OpenAI(api_key="sk-1234", base_url="http://localhost:4000")
|
||||
|
||||
# Define tools
|
||||
tools = [
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get the current weather",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {"type": "string"}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
|
||||
# Step 1: Initial request
|
||||
messages = [{"role": "user", "content": "What's the weather in Tokyo?"}]
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="gemini-3-pro-preview",
|
||||
messages=messages,
|
||||
tools=tools,
|
||||
reasoning_effort="low"
|
||||
)
|
||||
|
||||
# Step 2: Append assistant message (thought signatures automatically preserved)
|
||||
messages.append(response.choices[0].message)
|
||||
|
||||
# Step 3: Execute tool and append result
|
||||
for tool_call in response.choices[0].message.tool_calls:
|
||||
if tool_call.function.name == "get_weather":
|
||||
result = {"temperature": 30, "unit": "celsius"}
|
||||
messages.append({
|
||||
"role": "tool",
|
||||
"content": json.dumps(result),
|
||||
"tool_call_id": tool_call.id
|
||||
})
|
||||
|
||||
# Step 4: Follow-up request (thought signatures automatically included)
|
||||
response2 = client.chat.completions.create(
|
||||
model="gemini-3-pro-preview",
|
||||
messages=messages,
|
||||
tools=tools,
|
||||
reasoning_effort="low"
|
||||
)
|
||||
|
||||
print(response2.choices[0].message.content)
|
||||
```
|
||||
|
||||
**Key Points:**
|
||||
- ✅ Thought signatures are automatically extracted from `response.choices[0].message.tool_calls[].provider_specific_fields.thought_signature`
|
||||
- ✅ When you append `response.choices[0].message` to your conversation history, thought signatures are automatically preserved
|
||||
- ✅ You don't need to manually extract or manage thought signatures
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="cURL">
|
||||
|
||||
```bash
|
||||
# Step 1: Initial request
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gemini-3-pro-preview",
|
||||
"messages": [
|
||||
{"role": "user", "content": "What'\''s the weather in Tokyo?"}
|
||||
],
|
||||
"tools": [
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get the current weather",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {"type": "string"}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
}
|
||||
}
|
||||
],
|
||||
"reasoning_effort": "low"
|
||||
}'
|
||||
```
|
||||
|
||||
**Response includes thought signature:**
|
||||
|
||||
```json
|
||||
{
|
||||
"choices": [{
|
||||
"message": {
|
||||
"role": "assistant",
|
||||
"tool_calls": [{
|
||||
"id": "call_abc123",
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"arguments": "{\"location\": \"Tokyo\"}"
|
||||
},
|
||||
"provider_specific_fields": {
|
||||
"thought_signature": "CpcHAdHtim9+q4rstcbvQC0ic4x1/vqQlCJWgE+UZ6dTLYGHMMBkF/AxqL5UmP6SY46uYC8t4BTFiXG5zkw6EMJ..."
|
||||
}
|
||||
}]
|
||||
}
|
||||
}]
|
||||
}
|
||||
```
|
||||
|
||||
```bash
|
||||
# Step 2: Follow-up request (include assistant message with thought signature)
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gemini-3-pro-preview",
|
||||
"messages": [
|
||||
{"role": "user", "content": "What'\''s the weather in Tokyo?"},
|
||||
{
|
||||
"role": "assistant",
|
||||
"content": null,
|
||||
"tool_calls": [{
|
||||
"id": "call_abc123",
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"arguments": "{\"location\": \"Tokyo\"}"
|
||||
},
|
||||
"provider_specific_fields": {
|
||||
"thought_signature": "CpcHAdHtim9+q4rstcbvQC0ic4x1/vqQlCJWgE+UZ6dTLYGHMMBkF/AxqL5UmP6SY46uYC8t4BTFiXG5zkw6EMJ..."
|
||||
}
|
||||
}]
|
||||
},
|
||||
{
|
||||
"role": "tool",
|
||||
"content": "{\"temperature\": 30, \"unit\": \"celsius\"}",
|
||||
"tool_call_id": "call_abc123"
|
||||
}
|
||||
],
|
||||
"tools": [...],
|
||||
"reasoning_effort": "low"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
#### Important Notes on Thought Signatures
|
||||
|
||||
1. **Automatic Handling**: LiteLLM automatically extracts and preserves thought signatures. You don't need to manually manage them.
|
||||
|
||||
2. **Parallel Function Calls**: When the model makes parallel function calls, only the **first function call** has a thought signature.
|
||||
|
||||
3. **Sequential Function Calls**: In multi-step function calling, each step's first function call has its own thought signature that must be preserved.
|
||||
|
||||
4. **Required for Context**: Thought signatures are essential for maintaining reasoning context. Without them, the model may lose context of its previous reasoning.
|
||||
|
||||
## Conversation History: Switching from Non-Gemini-3 Models
|
||||
|
||||
#### Common Question: Will switching from a non-Gemini-3 model to Gemini-3 break conversation history?
|
||||
|
||||
**Answer: No!** LiteLLM automatically handles this by adding dummy thought signatures when needed.
|
||||
|
||||
#### How It Works
|
||||
|
||||
When you switch from a model that doesn't use thought signatures (e.g., `gemini-2.5-flash`) to Gemini 3, LiteLLM:
|
||||
|
||||
1. **Detects missing signatures**: Identifies assistant messages with tool calls that lack thought signatures
|
||||
2. **Adds dummy signature**: Automatically injects a dummy thought signature (`skip_thought_signature_validator`) for compatibility
|
||||
3. **Maintains conversation flow**: Your conversation history continues to work seamlessly
|
||||
|
||||
#### Example: Switching Models Mid-Conversation
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="Python SDK">
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(api_key="sk-1234", base_url="http://localhost:4000")
|
||||
|
||||
# Step 1: Start with gemini-2.5-flash (no thought signatures)
|
||||
messages = [{"role": "user", "content": "What's the weather?"}]
|
||||
|
||||
response1 = client.chat.completions.create(
|
||||
model="gemini-2.5-flash",
|
||||
messages=messages,
|
||||
tools=[...],
|
||||
reasoning_effort="low"
|
||||
)
|
||||
|
||||
# Append assistant message (no tool call thought signature from gemini-2.5-flash)
|
||||
messages.append(response1.choices[0].message)
|
||||
|
||||
# Step 2: Switch to gemini-3-pro-preview
|
||||
# LiteLLM automatically adds dummy thought signature to the previous assistant message
|
||||
response2 = client.chat.completions.create(
|
||||
model="gemini-3-pro-preview", # 👈 Switched model
|
||||
messages=messages, # 👈 Same conversation history
|
||||
tools=[...],
|
||||
reasoning_effort="low"
|
||||
)
|
||||
|
||||
# ✅ Works seamlessly! No errors, no breaking changes
|
||||
print(response2.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="cURL">
|
||||
|
||||
```bash
|
||||
# Step 1: Start with gemini-2.5-flash
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gemini-2.5-flash",
|
||||
"messages": [{"role": "user", "content": "What'\''s the weather?"}],
|
||||
"tools": [...],
|
||||
"reasoning_effort": "low"
|
||||
}'
|
||||
|
||||
# Step 2: Switch to gemini-3-pro-preview with same conversation history
|
||||
# LiteLLM automatically handles the missing thought signature
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gemini-3-pro-preview", # 👈 Switched model
|
||||
"messages": [
|
||||
{"role": "user", "content": "What'\''s the weather?"},
|
||||
{
|
||||
"role": "assistant",
|
||||
"tool_calls": [...] # 👈 No thought_signature from gemini-2.5-flash
|
||||
}
|
||||
],
|
||||
"tools": [...],
|
||||
"reasoning_effort": "low"
|
||||
}'
|
||||
# ✅ Works! LiteLLM adds dummy signature automatically
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
#### Dummy Signature Details
|
||||
|
||||
The dummy signature used is: `base64("skip_thought_signature_validator")`
|
||||
|
||||
This is the recommended approach by Google for handling conversation history from models that don't support thought signatures. It allows Gemini 3 to:
|
||||
- Accept the conversation history without validation errors
|
||||
- Continue the conversation seamlessly
|
||||
- Maintain context across model switches
|
||||
|
||||
## Thinking Level Parameter
|
||||
|
||||
#### How `reasoning_effort` Maps to `thinking_level`
|
||||
|
||||
For Gemini 3 Pro Preview, LiteLLM automatically maps `reasoning_effort` to the new `thinking_level` parameter:
|
||||
|
||||
| `reasoning_effort` | `thinking_level` | Notes |
|
||||
|-------------------|------------------|-------|
|
||||
| `"minimal"` | `"low"` | Maps to low thinking level |
|
||||
| `"low"` | `"low"` | Default for most use cases |
|
||||
| `"medium"` | `"high"` | Medium not available yet, maps to high |
|
||||
| `"high"` | `"high"` | Maximum reasoning depth |
|
||||
| `"disable"` | `"low"` | Gemini 3 cannot fully disable thinking |
|
||||
| `"none"` | `"low"` | Gemini 3 cannot fully disable thinking |
|
||||
|
||||
#### Default Behavior
|
||||
|
||||
If you don't specify `reasoning_effort`, LiteLLM automatically sets `thinking_level="low"` for Gemini 3 models, to avoid high costs.
|
||||
|
||||
### Example Usage
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="Python SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
# Low thinking level (faster, lower cost)
|
||||
response = completion(
|
||||
model="gemini/gemini-3-pro-preview",
|
||||
messages=[{"role": "user", "content": "What's the weather?"}],
|
||||
reasoning_effort="low" # Maps to thinking_level="low"
|
||||
)
|
||||
|
||||
# High thinking level (deeper reasoning, higher cost)
|
||||
response = completion(
|
||||
model="gemini/gemini-3-pro-preview",
|
||||
messages=[{"role": "user", "content": "Solve this complex math problem step by step."}],
|
||||
reasoning_effort="high" # Maps to thinking_level="high"
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
```bash
|
||||
# Low thinking level
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gemini-3-pro-preview",
|
||||
"messages": [{"role": "user", "content": "What'\''s the weather?"}],
|
||||
"reasoning_effort": "low"
|
||||
}'
|
||||
|
||||
# High thinking level
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gemini-3-pro-preview",
|
||||
"messages": [{"role": "user", "content": "Solve this complex problem."}],
|
||||
"reasoning_effort": "high"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Important Notes
|
||||
|
||||
1. **Gemini 3 Cannot Disable Thinking**: Unlike Gemini 2.5 models, Gemini 3 cannot fully disable thinking. Even when you set `reasoning_effort="none"` or `"disable"`, it maps to `thinking_level="low"`.
|
||||
|
||||
2. **Temperature Recommendation**: For Gemini 3 models, LiteLLM defaults `temperature` to `1.0` and strongly recommends keeping it at this default. Setting `temperature < 1.0` can cause:
|
||||
- Infinite loops
|
||||
- Degraded reasoning performance
|
||||
- Failure on complex tasks
|
||||
|
||||
3. **Automatic Defaults**: If you don't specify `reasoning_effort`, LiteLLM automatically sets `thinking_level="low"` for optimal performance.
|
||||
|
||||
## Cost Tracking: Prompt Caching & Context Window
|
||||
|
||||
LiteLLM provides comprehensive cost tracking for Gemini 3 Pro Preview, including support for prompt caching and tiered pricing based on context window size.
|
||||
|
||||
### Prompt Caching Cost Tracking
|
||||
|
||||
Gemini 3 supports prompt caching, which allows you to cache frequently used prompt prefixes to reduce costs. LiteLLM automatically tracks and calculates costs for:
|
||||
|
||||
- **Cache Hit Tokens**: Tokens that are read from cache (charged at a lower rate)
|
||||
- **Cache Creation Tokens**: Tokens that are written to cache (one-time cost)
|
||||
- **Text Tokens**: Regular prompt tokens that are processed normally
|
||||
|
||||
#### How It Works
|
||||
|
||||
LiteLLM extracts caching information from the `prompt_tokens_details` field in the usage object:
|
||||
|
||||
```python
|
||||
{
|
||||
"usage": {
|
||||
"prompt_tokens": 50000,
|
||||
"completion_tokens": 1000,
|
||||
"total_tokens": 51000,
|
||||
"prompt_tokens_details": {
|
||||
"cached_tokens": 30000, # Cache hit tokens
|
||||
"cache_creation_tokens": 5000, # Tokens written to cache
|
||||
"text_tokens": 15000 # Regular processed tokens
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Context Window Tiered Pricing
|
||||
|
||||
Gemini 3 Pro Preview supports up to 1M tokens of context, with tiered pricing that automatically applies when your prompt exceeds 200k tokens.
|
||||
|
||||
#### Automatic Tier Detection
|
||||
|
||||
LiteLLM automatically detects when your prompt exceeds the 200k token threshold and applies the appropriate tiered pricing:
|
||||
|
||||
```python
|
||||
from litellm import completion_cost
|
||||
|
||||
# Example: Small prompt (< 200k tokens)
|
||||
response_small = completion(
|
||||
model="gemini/gemini-3-pro-preview",
|
||||
messages=[{"role": "user", "content": "Hello!"}]
|
||||
)
|
||||
# Uses base pricing: $0.000002/input token, $0.000012/output token
|
||||
|
||||
# Example: Large prompt (> 200k tokens)
|
||||
response_large = completion(
|
||||
model="gemini/gemini-3-pro-preview",
|
||||
messages=[{"role": "user", "content": "..." * 250000}] # 250k tokens
|
||||
)
|
||||
# Automatically uses tiered pricing: $0.000004/input token, $0.000018/output token
|
||||
```
|
||||
|
||||
#### Cost Breakdown
|
||||
|
||||
The cost calculation includes:
|
||||
|
||||
1. **Text Processing Cost**: Regular tokens processed at base or tiered rate
|
||||
2. **Cache Read Cost**: Cached tokens read at discounted rate
|
||||
3. **Cache Creation Cost**: One-time cost for writing tokens to cache (applies tiered rate if above 200k)
|
||||
4. **Output Cost**: Generated tokens at base or tiered rate
|
||||
|
||||
### Example: Viewing Cost Breakdown
|
||||
|
||||
You can view the detailed cost breakdown using LiteLLM's cost tracking:
|
||||
|
||||
```python
|
||||
from litellm import completion, completion_cost
|
||||
|
||||
response = completion(
|
||||
model="gemini/gemini-3-pro-preview",
|
||||
messages=[{"role": "user", "content": "Explain prompt caching"}],
|
||||
caching=True # Enable prompt caching
|
||||
)
|
||||
|
||||
# Get total cost
|
||||
total_cost = completion_cost(completion_response=response)
|
||||
print(f"Total cost: ${total_cost:.6f}")
|
||||
|
||||
# Access usage details
|
||||
usage = response.usage
|
||||
print(f"Prompt tokens: {usage.prompt_tokens}")
|
||||
print(f"Completion tokens: {usage.completion_tokens}")
|
||||
|
||||
# Access caching details
|
||||
if usage.prompt_tokens_details:
|
||||
print(f"Cache hit tokens: {usage.prompt_tokens_details.cached_tokens}")
|
||||
print(f"Cache creation tokens: {usage.prompt_tokens_details.cache_creation_tokens}")
|
||||
print(f"Text tokens: {usage.prompt_tokens_details.text_tokens}")
|
||||
```
|
||||
|
||||
### Cost Optimization Tips
|
||||
|
||||
1. **Use Prompt Caching**: For repeated prompt prefixes, enable caching to reduce costs by up to 90% for cached portions
|
||||
2. **Monitor Context Size**: Be aware that prompts above 200k tokens use tiered pricing (2x for input, 1.5x for output)
|
||||
3. **Cache Management**: Cache creation tokens are charged once when writing to cache, then subsequent reads are much cheaper
|
||||
4. **Track Usage**: Use LiteLLM's built-in cost tracking to monitor spending across different token types
|
||||
|
||||
### Integration with LiteLLM Proxy
|
||||
|
||||
When using LiteLLM Proxy, all cost tracking is automatically logged and available through:
|
||||
|
||||
- **Usage Logs**: Detailed token and cost breakdowns in proxy logs
|
||||
- **Budget Management**: Set budgets and alerts based on actual usage
|
||||
- **Analytics Dashboard**: View cost trends and breakdowns by token type
|
||||
|
||||
```yaml
|
||||
# config.yaml
|
||||
model_list:
|
||||
- model_name: gemini-3-pro-preview
|
||||
litellm_params:
|
||||
model: gemini/gemini-3-pro-preview
|
||||
api_key: os.environ/GEMINI_API_KEY
|
||||
|
||||
litellm_settings:
|
||||
# Enable detailed cost tracking
|
||||
success_callback: ["langfuse"] # or your preferred logging service
|
||||
```
|
||||
|
||||
## Using with Claude Code CLI
|
||||
|
||||
You can use `gemini-3-pro-preview` with **Claude Code CLI** - Anthropic's command-line interface. This allows you to use Gemini 3 Pro Preview with Claude Code's native syntax and workflows.
|
||||
|
||||
### Setup
|
||||
|
||||
**1. Add Gemini 3 Pro Preview to your `config.yaml`:**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gemini-3-pro-preview
|
||||
litellm_params:
|
||||
model: gemini/gemini-3-pro-preview
|
||||
api_key: os.environ/GEMINI_API_KEY
|
||||
|
||||
litellm_settings:
|
||||
master_key: os.environ/LITELLM_MASTER_KEY
|
||||
```
|
||||
|
||||
**2. Set environment variables:**
|
||||
|
||||
```bash
|
||||
export GEMINI_API_KEY="your-gemini-api-key"
|
||||
export LITELLM_MASTER_KEY="sk-1234567890" # Generate a secure key
|
||||
```
|
||||
|
||||
**3. Start LiteLLM Proxy:**
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
**4. Configure Claude Code to use LiteLLM Proxy:**
|
||||
|
||||
```bash
|
||||
export ANTHROPIC_BASE_URL="http://0.0.0.0:4000"
|
||||
export ANTHROPIC_AUTH_TOKEN="$LITELLM_MASTER_KEY"
|
||||
```
|
||||
|
||||
**5. Use Gemini 3 Pro Preview with Claude Code:**
|
||||
|
||||
```bash
|
||||
# Claude Code will use gemini-3-pro-preview from your LiteLLM proxy
|
||||
claude --model gemini-3-pro-preview
|
||||
|
||||
```
|
||||
|
||||
### Example Usage
|
||||
|
||||
Once configured, you can interact with Gemini 3 Pro Preview using Claude Code's native interface:
|
||||
|
||||
```bash
|
||||
$ claude --model gemini-3-pro-preview
|
||||
> Explain how thought signatures work in multi-turn conversations.
|
||||
|
||||
# Gemini 3 Pro Preview responds through Claude Code interface
|
||||
```
|
||||
|
||||
### Benefits
|
||||
|
||||
- ✅ **Native Claude Code Experience**: Use Gemini 3 Pro Preview with Claude Code's familiar CLI interface
|
||||
- ✅ **Unified Authentication**: Single API key for all models through LiteLLM proxy
|
||||
- ✅ **Cost Tracking**: All usage tracked through LiteLLM's centralized logging
|
||||
- ✅ **Seamless Model Switching**: Easily switch between Claude and Gemini models
|
||||
- ✅ **Full Feature Support**: All Gemini 3 features (thought signatures, function calling, etc.) work through Claude Code
|
||||
|
||||
### Troubleshooting
|
||||
|
||||
**Claude Code not finding the model:**
|
||||
- Ensure the model name in Claude Code matches exactly: `gemini-3-pro-preview`
|
||||
- Verify your proxy is running: `curl http://0.0.0.0:4000/health`
|
||||
- Check that `ANTHROPIC_BASE_URL` points to your LiteLLM proxy
|
||||
|
||||
**Authentication errors:**
|
||||
- Verify `ANTHROPIC_AUTH_TOKEN` matches your LiteLLM master key
|
||||
- Ensure `GEMINI_API_KEY` is set correctly
|
||||
- Check LiteLLM proxy logs for detailed error messages
|
||||
|
||||
## Responses API Support
|
||||
|
||||
LiteLLM fully supports the OpenAI Responses API for Gemini 3 Pro Preview, including both streaming and non-streaming modes. The Responses API provides a structured way to handle multi-turn conversations with function calling, and LiteLLM automatically preserves thought signatures throughout the conversation.
|
||||
|
||||
### Example: Using Responses API with Gemini 3
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="Non-Streaming">
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
import json
|
||||
|
||||
client = OpenAI()
|
||||
|
||||
# 1. Define a list of callable tools for the model
|
||||
tools = [
|
||||
{
|
||||
"type": "function",
|
||||
"name": "get_horoscope",
|
||||
"description": "Get today's horoscope for an astrological sign.",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"sign": {
|
||||
"type": "string",
|
||||
"description": "An astrological sign like Taurus or Aquarius",
|
||||
},
|
||||
},
|
||||
"required": ["sign"],
|
||||
},
|
||||
},
|
||||
]
|
||||
|
||||
def get_horoscope(sign):
|
||||
return f"{sign}: Next Tuesday you will befriend a baby otter."
|
||||
|
||||
# Create a running input list we will add to over time
|
||||
input_list = [
|
||||
{"role": "user", "content": "What is my horoscope? I am an Aquarius."}
|
||||
]
|
||||
|
||||
# 2. Prompt the model with tools defined
|
||||
response = client.responses.create(
|
||||
model="gemini-3-pro-preview",
|
||||
tools=tools,
|
||||
input=input_list,
|
||||
)
|
||||
|
||||
# Save function call outputs for subsequent requests
|
||||
input_list += response.output
|
||||
|
||||
for item in response.output:
|
||||
if item.type == "function_call":
|
||||
if item.name == "get_horoscope":
|
||||
# 3. Execute the function logic for get_horoscope
|
||||
horoscope = get_horoscope(json.loads(item.arguments))
|
||||
|
||||
# 4. Provide function call results to the model
|
||||
input_list.append({
|
||||
"type": "function_call_output",
|
||||
"call_id": item.call_id,
|
||||
"output": json.dumps({
|
||||
"horoscope": horoscope
|
||||
})
|
||||
})
|
||||
|
||||
print("Final input:")
|
||||
print(input_list)
|
||||
|
||||
response = client.responses.create(
|
||||
model="gemini-3-pro-preview",
|
||||
instructions="Respond only with a horoscope generated by a tool.",
|
||||
tools=tools,
|
||||
input=input_list,
|
||||
)
|
||||
|
||||
# 5. The model should be able to give a response!
|
||||
print("Final output:")
|
||||
print(response.model_dump_json(indent=2))
|
||||
print("\n" + response.output_text)
|
||||
```
|
||||
|
||||
**Key Points:**
|
||||
- ✅ Thought signatures are automatically preserved in function calls
|
||||
- ✅ Works seamlessly with multi-turn conversations
|
||||
- ✅ All Gemini 3-specific features are fully supported
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="streaming" label="Streaming">
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
import json
|
||||
|
||||
client = OpenAI()
|
||||
|
||||
tools = [
|
||||
{
|
||||
"type": "function",
|
||||
"name": "get_horoscope",
|
||||
"description": "Get today's horoscope for an astrological sign.",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"sign": {
|
||||
"type": "string",
|
||||
"description": "An astrological sign like Taurus or Aquarius",
|
||||
},
|
||||
},
|
||||
"required": ["sign"],
|
||||
},
|
||||
},
|
||||
]
|
||||
|
||||
def get_horoscope(sign):
|
||||
return f"{sign}: Next Tuesday you will befriend a baby otter."
|
||||
|
||||
input_list = [
|
||||
{"role": "user", "content": "What is my horoscope? I am an Aquarius."}
|
||||
]
|
||||
|
||||
# Streaming mode
|
||||
response = client.responses.create(
|
||||
model="gemini-3-pro-preview",
|
||||
tools=tools,
|
||||
input=input_list,
|
||||
stream=True,
|
||||
)
|
||||
|
||||
# Collect all chunks
|
||||
chunks = []
|
||||
for chunk in response:
|
||||
chunks.append(chunk)
|
||||
# Process streaming chunks as they arrive
|
||||
print(chunk)
|
||||
|
||||
# Thought signatures are automatically preserved in streaming mode
|
||||
```
|
||||
|
||||
**Key Points:**
|
||||
- ✅ Streaming mode fully supported
|
||||
- ✅ Thought signatures preserved across streaming chunks
|
||||
- ✅ Real-time processing of function calls and responses
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Responses API Benefits
|
||||
|
||||
- ✅ **Structured Output**: Responses API provides a clear structure for handling function calls and multi-turn conversations
|
||||
- ✅ **Thought Signature Preservation**: LiteLLM automatically preserves thought signatures in both streaming and non-streaming modes
|
||||
- ✅ **Seamless Integration**: Works with existing OpenAI SDK patterns
|
||||
- ✅ **Full Feature Support**: All Gemini 3 features (thought signatures, function calling, reasoning) are fully supported
|
||||
|
||||
|
||||
## Best Practices
|
||||
|
||||
#### 1. Always Include Thought Signatures in Conversation History
|
||||
|
||||
When building multi-turn conversations with function calling:
|
||||
|
||||
✅ **Do:**
|
||||
```python
|
||||
# Append the full assistant message (includes thought signatures)
|
||||
messages.append(response.choices[0].message)
|
||||
```
|
||||
|
||||
❌ **Don't:**
|
||||
```python
|
||||
# Don't manually construct assistant messages without thought signatures
|
||||
messages.append({
|
||||
"role": "assistant",
|
||||
"tool_calls": [...] # Missing thought signatures!
|
||||
})
|
||||
```
|
||||
|
||||
#### 2. Use Appropriate Thinking Levels
|
||||
|
||||
- **`reasoning_effort="low"`**: For simple queries, quick responses, cost optimization
|
||||
- **`reasoning_effort="high"`**: For complex problems requiring deep reasoning
|
||||
|
||||
#### 3. Keep Temperature at Default
|
||||
|
||||
For Gemini 3 models, always use `temperature=1.0` (default). Lower temperatures can cause issues.
|
||||
|
||||
#### 4. Handle Model Switches Gracefully
|
||||
|
||||
When switching from non-Gemini-3 to Gemini-3:
|
||||
- ✅ LiteLLM automatically handles missing thought signatures
|
||||
- ✅ No manual intervention needed
|
||||
- ✅ Conversation history continues seamlessly
|
||||
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
#### Issue: Missing Thought Signatures
|
||||
|
||||
**Symptom**: Error when including assistant messages in conversation history
|
||||
|
||||
**Solution**: Ensure you're appending the full assistant message from the response:
|
||||
```python
|
||||
messages.append(response.choices[0].message) # ✅ Includes thought signatures
|
||||
```
|
||||
|
||||
#### Issue: Conversation Breaks When Switching Models
|
||||
|
||||
**Symptom**: Errors when switching from gemini-2.5-flash to gemini-3-pro-preview
|
||||
|
||||
**Solution**: This should work automatically! LiteLLM adds dummy signatures. If you see errors, ensure you're using the latest LiteLLM version.
|
||||
|
||||
#### Issue: Infinite Loops or Poor Performance
|
||||
|
||||
**Symptom**: Model gets stuck or produces poor results
|
||||
|
||||
**Solution**:
|
||||
- Ensure `temperature=1.0` (default for Gemini 3)
|
||||
- Check that `reasoning_effort` is set appropriately
|
||||
- Verify you're using the correct model name: `gemini/gemini-3-pro-preview`
|
||||
|
||||
## Additional Resources
|
||||
|
||||
- [Gemini Provider Documentation](../gemini.md)
|
||||
- [Thought Signatures Guide](../gemini.md#thought-signatures)
|
||||
- [Reasoning Content Documentation](../../reasoning_content.md)
|
||||
- [Function Calling Guide](../../function_calling.md)
|
||||
|
||||
232
docs/my-website/docs/a2a.md
Normal file
232
docs/my-website/docs/a2a.md
Normal file
|
|
@ -0,0 +1,232 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Agent Gateway (A2A Protocol) - Overview
|
||||
|
||||
Add A2A Agents on LiteLLM AI Gateway, Invoke agents in A2A Protocol, track request/response logs in LiteLLM Logs. Manage which Teams, Keys can access which Agents onboarded.
|
||||
|
||||
<Image
|
||||
img={require('../img/a2a_gateway.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0', borderRadius: '8px'}}
|
||||
/>
|
||||
|
||||
<br />
|
||||
<br />
|
||||
|
||||
| Feature | Supported |
|
||||
|---------|-----------|
|
||||
| Logging | ✅ |
|
||||
| Load Balancing | ✅ |
|
||||
| Streaming | ✅ |
|
||||
|
||||
:::tip
|
||||
|
||||
LiteLLM follows the [A2A (Agent-to-Agent) Protocol](https://github.com/google/A2A) for invoking agents.
|
||||
|
||||
:::
|
||||
|
||||
## Adding your Agent
|
||||
|
||||
You can add A2A-compatible agents through the LiteLLM Admin UI.
|
||||
|
||||
1. Navigate to the **Agents** tab
|
||||
2. Click **Add Agent**
|
||||
3. Enter the agent name (e.g., `ij-local`) and the URL of your A2A agent
|
||||
|
||||
<Image
|
||||
img={require('../img/add_agent_1.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0'}}
|
||||
/>
|
||||
|
||||
The URL should be the invocation URL for your A2A agent (e.g., `http://localhost:10001`).
|
||||
|
||||
## Invoking your Agents
|
||||
|
||||
Use the [A2A Python SDK](https://pypi.org/project/a2a/) to invoke agents through LiteLLM.
|
||||
|
||||
This example shows how to:
|
||||
1. **List available agents** - Query `/v1/agents` to see which agents your key can access
|
||||
2. **Select an agent** - Pick an agent from the list
|
||||
3. **Invoke via A2A** - Use the A2A protocol to send messages to the agent
|
||||
|
||||
```python showLineNumbers title="invoke_a2a_agent.py"
|
||||
from uuid import uuid4
|
||||
import httpx
|
||||
import asyncio
|
||||
from a2a.client import A2ACardResolver, A2AClient
|
||||
from a2a.types import MessageSendParams, SendMessageRequest
|
||||
|
||||
# === CONFIGURE THESE ===
|
||||
LITELLM_BASE_URL = "http://localhost:4000" # Your LiteLLM proxy URL
|
||||
LITELLM_VIRTUAL_KEY = "sk-1234" # Your LiteLLM Virtual Key
|
||||
# =======================
|
||||
|
||||
async def main():
|
||||
headers = {"Authorization": f"Bearer {LITELLM_VIRTUAL_KEY}"}
|
||||
|
||||
async with httpx.AsyncClient(headers=headers) as client:
|
||||
# Step 1: List available agents
|
||||
response = await client.get(f"{LITELLM_BASE_URL}/v1/agents")
|
||||
agents = response.json()
|
||||
|
||||
print("Available agents:")
|
||||
for agent in agents:
|
||||
print(f" - {agent['agent_name']} (ID: {agent['agent_id']})")
|
||||
|
||||
if not agents:
|
||||
print("No agents available for this key")
|
||||
return
|
||||
|
||||
# Step 2: Select an agent and invoke it
|
||||
selected_agent = agents[0]
|
||||
agent_id = selected_agent["agent_id"]
|
||||
agent_name = selected_agent["agent_name"]
|
||||
print(f"\nInvoking: {agent_name}")
|
||||
|
||||
# Step 3: Use A2A protocol to invoke the agent
|
||||
base_url = f"{LITELLM_BASE_URL}/a2a/{agent_id}"
|
||||
resolver = A2ACardResolver(httpx_client=client, base_url=base_url)
|
||||
agent_card = await resolver.get_agent_card()
|
||||
a2a_client = A2AClient(httpx_client=client, agent_card=agent_card)
|
||||
|
||||
request = SendMessageRequest(
|
||||
id=str(uuid4()),
|
||||
params=MessageSendParams(
|
||||
message={
|
||||
"role": "user",
|
||||
"parts": [{"kind": "text", "text": "Hello, what can you do?"}],
|
||||
"messageId": uuid4().hex,
|
||||
}
|
||||
),
|
||||
)
|
||||
response = await a2a_client.send_message(request)
|
||||
print(f"Response: {response.model_dump(mode='json', exclude_none=True, indent=4)}")
|
||||
|
||||
if __name__ == "__main__":
|
||||
asyncio.run(main())
|
||||
```
|
||||
|
||||
### Streaming Responses
|
||||
|
||||
For streaming responses, use `send_message_streaming`:
|
||||
|
||||
```python showLineNumbers title="invoke_a2a_agent_streaming.py"
|
||||
from uuid import uuid4
|
||||
import httpx
|
||||
import asyncio
|
||||
from a2a.client import A2ACardResolver, A2AClient
|
||||
from a2a.types import MessageSendParams, SendStreamingMessageRequest
|
||||
|
||||
# === CONFIGURE THESE ===
|
||||
LITELLM_BASE_URL = "http://localhost:4000" # Your LiteLLM proxy URL
|
||||
LITELLM_VIRTUAL_KEY = "sk-1234" # Your LiteLLM Virtual Key
|
||||
LITELLM_AGENT_NAME = "ij-local" # Agent name registered in LiteLLM
|
||||
# =======================
|
||||
|
||||
async def main():
|
||||
base_url = f"{LITELLM_BASE_URL}/a2a/{LITELLM_AGENT_NAME}"
|
||||
headers = {"Authorization": f"Bearer {LITELLM_VIRTUAL_KEY}"}
|
||||
|
||||
async with httpx.AsyncClient(headers=headers) as httpx_client:
|
||||
# Resolve agent card and create client
|
||||
resolver = A2ACardResolver(httpx_client=httpx_client, base_url=base_url)
|
||||
agent_card = await resolver.get_agent_card()
|
||||
client = A2AClient(httpx_client=httpx_client, agent_card=agent_card)
|
||||
|
||||
# Send a streaming message
|
||||
request = SendStreamingMessageRequest(
|
||||
id=str(uuid4()),
|
||||
params=MessageSendParams(
|
||||
message={
|
||||
"role": "user",
|
||||
"parts": [{"kind": "text", "text": "Hello, what can you do?"}],
|
||||
"messageId": uuid4().hex,
|
||||
}
|
||||
),
|
||||
)
|
||||
|
||||
# Stream the response
|
||||
async for chunk in client.send_message_streaming(request):
|
||||
print(chunk.model_dump(mode="json", exclude_none=True))
|
||||
|
||||
if __name__ == "__main__":
|
||||
asyncio.run(main())
|
||||
```
|
||||
|
||||
## Tracking Agent Logs
|
||||
|
||||
After invoking an agent, you can view the request logs in the LiteLLM **Logs** tab.
|
||||
|
||||
The logs show:
|
||||
- **Request/Response content** sent to and received from the agent
|
||||
- **User, Key, Team** information for tracking who made the request
|
||||
- **Latency and cost** metrics
|
||||
|
||||
<Image
|
||||
img={require('../img/agent2.png')}
|
||||
style={{width: '100%', display: 'block', margin: '2rem auto'}}
|
||||
/>
|
||||
|
||||
## API Reference
|
||||
|
||||
### Endpoint
|
||||
|
||||
```
|
||||
POST /a2a/{agent_name}/message/send
|
||||
```
|
||||
|
||||
### Authentication
|
||||
|
||||
Include your LiteLLM Virtual Key in the `Authorization` header:
|
||||
|
||||
```
|
||||
Authorization: Bearer sk-your-litellm-key
|
||||
```
|
||||
|
||||
### Request Format
|
||||
|
||||
LiteLLM follows the [A2A JSON-RPC 2.0 specification](https://github.com/google/A2A):
|
||||
|
||||
```json title="Request Body"
|
||||
{
|
||||
"jsonrpc": "2.0",
|
||||
"id": "unique-request-id",
|
||||
"method": "message/send",
|
||||
"params": {
|
||||
"message": {
|
||||
"role": "user",
|
||||
"parts": [{"kind": "text", "text": "Your message here"}],
|
||||
"messageId": "unique-message-id"
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Response Format
|
||||
|
||||
```json title="Response"
|
||||
{
|
||||
"jsonrpc": "2.0",
|
||||
"id": "unique-request-id",
|
||||
"result": {
|
||||
"kind": "task",
|
||||
"id": "task-id",
|
||||
"contextId": "context-id",
|
||||
"status": {"state": "completed", "timestamp": "2025-01-01T00:00:00Z"},
|
||||
"artifacts": [
|
||||
{
|
||||
"artifactId": "artifact-id",
|
||||
"name": "response",
|
||||
"parts": [{"kind": "text", "text": "Agent response here"}]
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Agent Registry
|
||||
|
||||
Want to create a central registry so your team can discover what agents are available within your company?
|
||||
|
||||
Use the [AI Hub](./proxy/ai_hub) to make agents public and discoverable across your organization. This allows developers to browse available agents without needing to rebuild them.
|
||||
259
docs/my-website/docs/a2a_agent_permissions.md
Normal file
259
docs/my-website/docs/a2a_agent_permissions.md
Normal file
|
|
@ -0,0 +1,259 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Agent Permission Management
|
||||
|
||||
Control which A2A agents can be accessed by specific keys or teams in LiteLLM.
|
||||
|
||||
## Overview
|
||||
|
||||
Agent Permission Management lets you restrict which agents a LiteLLM Virtual Key or Team can access. This is useful for:
|
||||
|
||||
- **Multi-tenant environments**: Give different teams access to different agents
|
||||
- **Security**: Prevent keys from invoking agents they shouldn't have access to
|
||||
- **Compliance**: Enforce access policies for sensitive agent workflows
|
||||
|
||||
When permissions are configured:
|
||||
- `GET /v1/agents` only returns agents the key/team can access
|
||||
- `POST /a2a/{agent_id}` (Invoking an agent) returns `403 Forbidden` if access is denied
|
||||
|
||||
## Setting Permissions on a Key
|
||||
|
||||
This example shows how to create a key with agent permissions and test access.
|
||||
|
||||
### 1. Get Your Agent ID
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI">
|
||||
|
||||
1. Go to **Agents** in the sidebar
|
||||
2. Click into the agent you want
|
||||
3. Copy the **Agent ID**
|
||||
|
||||
<Image
|
||||
img={require('../img/agent_id.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0', borderRadius: '8px'}}
|
||||
/>
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
```bash title="List all agents" showLineNumbers
|
||||
curl "http://localhost:4000/v1/agents" \
|
||||
-H "Authorization: Bearer sk-master-key"
|
||||
```
|
||||
|
||||
Response:
|
||||
```json title="Response" showLineNumbers
|
||||
{
|
||||
"agents": [
|
||||
{"agent_id": "agent-123", "name": "Support Agent"},
|
||||
{"agent_id": "agent-456", "name": "Sales Agent"}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### 2. Create a Key with Agent Permissions
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI">
|
||||
|
||||
1. Go to **Keys** → **Create Key**
|
||||
2. Expand **Agent Settings**
|
||||
3. Select the agents you want to allow
|
||||
|
||||
<Image
|
||||
img={require('../img/agent_key.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0', borderRadius: '8px'}}
|
||||
/>
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
```bash title="Create key with agent permissions" showLineNumbers
|
||||
curl -X POST "http://localhost:4000/key/generate" \
|
||||
-H "Authorization: Bearer sk-master-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"object_permission": {
|
||||
"agents": ["agent-123"]
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### 3. Test Access
|
||||
|
||||
**Allowed agent (succeeds):**
|
||||
```bash title="Invoke allowed agent" showLineNumbers
|
||||
curl -X POST "http://localhost:4000/a2a/agent-123" \
|
||||
-H "Authorization: Bearer sk-your-new-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"message": {"role": "user", "parts": [{"type": "text", "text": "Hello"}]}}'
|
||||
```
|
||||
|
||||
**Blocked agent (fails with 403):**
|
||||
```bash title="Invoke blocked agent" showLineNumbers
|
||||
curl -X POST "http://localhost:4000/a2a/agent-456" \
|
||||
-H "Authorization: Bearer sk-your-new-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"message": {"role": "user", "parts": [{"type": "text", "text": "Hello"}]}}'
|
||||
```
|
||||
|
||||
Response:
|
||||
```json title="403 Forbidden Response" showLineNumbers
|
||||
{
|
||||
"error": {
|
||||
"message": "Access denied to agent: agent-456",
|
||||
"code": 403
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Setting Permissions on a Team
|
||||
|
||||
Restrict all keys belonging to a team to only access specific agents.
|
||||
|
||||
### 1. Create a Team with Agent Permissions
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI">
|
||||
|
||||
1. Go to **Teams** → **Create Team**
|
||||
2. Expand **Agent Settings**
|
||||
3. Select the agents you want to allow for this team
|
||||
|
||||
<Image
|
||||
img={require('../img/agent_key.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0', borderRadius: '8px'}}
|
||||
/>
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
```bash title="Create team with agent permissions" showLineNumbers
|
||||
curl -X POST "http://localhost:4000/team/new" \
|
||||
-H "Authorization: Bearer sk-master-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"team_alias": "support-team",
|
||||
"object_permission": {
|
||||
"agents": ["agent-123"]
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
Response:
|
||||
```json title="Response" showLineNumbers
|
||||
{
|
||||
"team_id": "team-abc-123",
|
||||
"team_alias": "support-team"
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### 2. Create a Key for the Team
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI">
|
||||
|
||||
1. Go to **Keys** → **Create Key**
|
||||
2. Select the **Team** from the dropdown
|
||||
|
||||
<Image
|
||||
img={require('../img/agent_team.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0', borderRadius: '8px'}}
|
||||
/>
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
```bash title="Create key for team" showLineNumbers
|
||||
curl -X POST "http://localhost:4000/key/generate" \
|
||||
-H "Authorization: Bearer sk-master-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"team_id": "team-abc-123"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### 3. Test Access
|
||||
|
||||
The key inherits agent permissions from the team.
|
||||
|
||||
**Allowed agent (succeeds):**
|
||||
```bash title="Invoke allowed agent" showLineNumbers
|
||||
curl -X POST "http://localhost:4000/a2a/agent-123" \
|
||||
-H "Authorization: Bearer sk-team-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"message": {"role": "user", "parts": [{"type": "text", "text": "Hello"}]}}'
|
||||
```
|
||||
|
||||
**Blocked agent (fails with 403):**
|
||||
```bash title="Invoke blocked agent" showLineNumbers
|
||||
curl -X POST "http://localhost:4000/a2a/agent-456" \
|
||||
-H "Authorization: Bearer sk-team-key" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"message": {"role": "user", "parts": [{"type": "text", "text": "Hello"}]}}'
|
||||
```
|
||||
|
||||
## How It Works
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
A[Request to invoke agent] --> B{LiteLLM Virtual Key has agent restrictions?}
|
||||
B -->|Yes| C{LiteLLM Team has agent restrictions?}
|
||||
B -->|No| D{LiteLLM Team has agent restrictions?}
|
||||
|
||||
C -->|Yes| E[Use intersection of key + team permissions]
|
||||
C -->|No| F[Use key permissions only]
|
||||
|
||||
D -->|Yes| G[Inherit team permissions]
|
||||
D -->|No| H[Allow ALL agents]
|
||||
|
||||
E --> I{Agent in allowed list?}
|
||||
F --> I
|
||||
G --> I
|
||||
H --> J[Allow request]
|
||||
|
||||
I -->|Yes| J
|
||||
I -->|No| K[Return 403 Forbidden]
|
||||
```
|
||||
|
||||
| Key Permissions | Team Permissions | Result | Notes |
|
||||
|-----------------|------------------|--------|-------|
|
||||
| None | None | Key can access **all** agents | Open access by default when no restrictions are set |
|
||||
| `["agent-1", "agent-2"]` | None | Key can access `agent-1` and `agent-2` | Key uses its own permissions |
|
||||
| None | `["agent-1", "agent-3"]` | Key can access `agent-1` and `agent-3` | Key inherits team's permissions |
|
||||
| `["agent-1", "agent-2"]` | `["agent-1", "agent-3"]` | Key can access `agent-1` only | Intersection of both lists (most restrictive wins) |
|
||||
|
||||
## Viewing Permissions
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI">
|
||||
|
||||
1. Go to **Keys** or **Teams**
|
||||
2. Click into the key/team you want to view
|
||||
3. Agent permissions are displayed in the info view
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
```bash title="Get key info" showLineNumbers
|
||||
curl "http://localhost:4000/key/info?key=sk-your-key" \
|
||||
-H "Authorization: Bearer sk-master-key"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
147
docs/my-website/docs/a2a_cost_tracking.md
Normal file
147
docs/my-website/docs/a2a_cost_tracking.md
Normal file
|
|
@ -0,0 +1,147 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
# A2A Agent Cost Tracking
|
||||
|
||||
LiteLLM supports adding custom cost tracking for A2A agents. You can configure:
|
||||
|
||||
- **Flat cost per query** - A fixed cost charged for each agent request
|
||||
- **Cost by input/output tokens** - Variable cost based on token usage
|
||||
|
||||
This allows you to track and attribute costs for agent usage across your organization, making it easy to see how much each team or project is spending on agent calls.
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Navigate to Agents
|
||||
|
||||
From the sidebar, click on "Agents" to open the agent management page.
|
||||
|
||||
|
||||
|
||||
### 2. Create a New Agent
|
||||
|
||||
Click "+ Add New Agent" to open the creation form. You'll need to provide a few basic details:
|
||||
|
||||
- **Agent Name** - A unique identifier for your agent (used in API calls)
|
||||
- **Display Name** - A human-readable name shown in the UI
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
### 3. Configure Cost Settings
|
||||
|
||||
Scroll down and click on "Cost Configuration" to expand the cost settings panel. This is where you define how much to charge for agent usage.
|
||||
|
||||
|
||||
|
||||
### 4. Set Cost Per Query
|
||||
|
||||
Enter the cost per query amount (in dollars). For example, entering `0.05` means each request to this agent will be charged $0.05.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
### 5. Create the Agent
|
||||
|
||||
Once you've configured everything, click "Create Agent" to save. Your agent is now ready to use with cost tracking enabled.
|
||||
|
||||

|
||||
|
||||
## Testing Cost Tracking
|
||||
|
||||
Let's verify that cost tracking is working by sending a test request through the Playground.
|
||||
|
||||
### 1. Go to Playground
|
||||
|
||||
Click "Playground" in the sidebar to open the interactive testing interface.
|
||||
|
||||
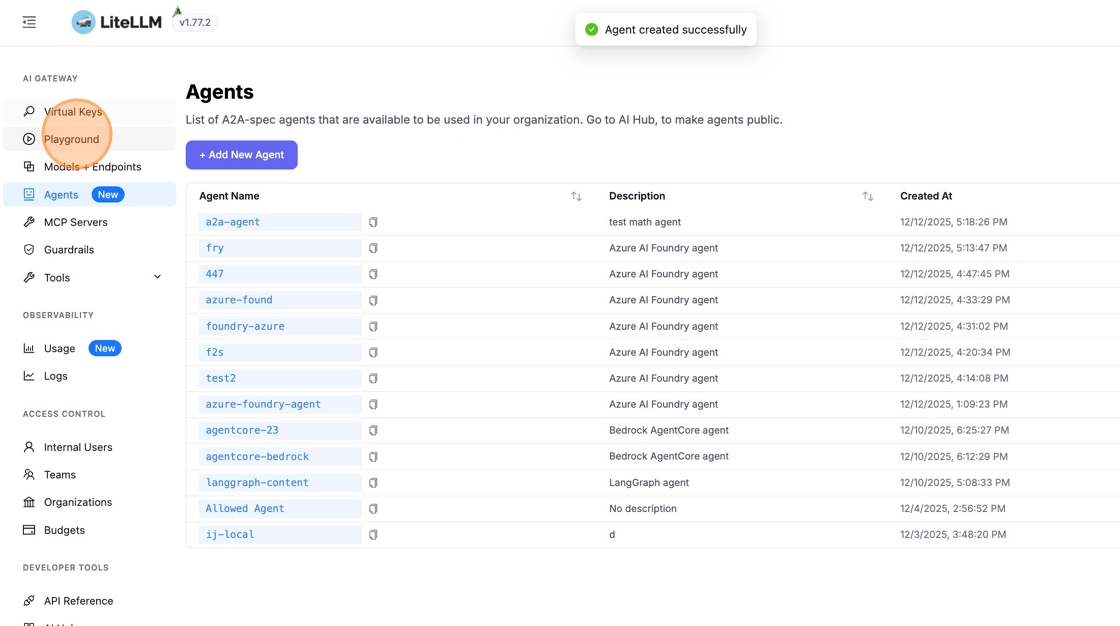
|
||||
|
||||
### 2. Select A2A Endpoint
|
||||
|
||||
By default, the Playground uses the chat completions endpoint. To test your agent, click "Endpoint Type" and select `/v1/a2a/message/send` from the dropdown.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
### 3. Select Your Agent
|
||||
|
||||
Now pick the agent you just created from the agent dropdown. You should see it listed by its display name.
|
||||
|
||||

|
||||
|
||||
### 4. Send a Test Message
|
||||
|
||||
Type a message and hit send. You can use the suggested prompts or write your own.
|
||||
|
||||
|
||||
|
||||
Once the agent responds, the request is logged with the cost you configured.
|
||||
|
||||
|
||||
|
||||
## Viewing Cost in Logs
|
||||
|
||||
Now let's confirm the cost was actually tracked.
|
||||
|
||||
### 1. Navigate to Logs
|
||||
|
||||
Click "Logs" in the sidebar to see all recent requests.
|
||||
|
||||
|
||||
|
||||
### 2. View Cost Attribution
|
||||
|
||||
Find your agent request in the list. You'll see the cost column showing the amount you configured. This cost is now attributed to the API key that made the request, so you can track spend per team or project.
|
||||
|
||||
|
||||
|
||||
## View Spend in Usage Page
|
||||
|
||||
Navigate to the Agent Usage tab in the Admin UI to view agent-level spend analytics:
|
||||
|
||||
### 1. Access Agent Usage
|
||||
|
||||
Go to the Usage page in the Admin UI (`PROXY_BASE_URL/ui/?login=success&page=new_usage`) and click on the **Agent Usage** tab.
|
||||
|
||||
<Image img={require('../img/agent_usage_ui_navigation.png')} />
|
||||
|
||||
### 2. View Agent Analytics
|
||||
|
||||
The Agent Usage dashboard provides:
|
||||
|
||||
- **Total spend per agent**: View aggregated spend across all agents
|
||||
- **Daily spend trends**: See how agent spend changes over time
|
||||
- **Model usage breakdown**: Understand which models each agent uses
|
||||
- **Activity metrics**: Track requests, tokens, and success rates per agent
|
||||
|
||||
<Image img={require('../img/agent_usage_analytics.png')} />
|
||||
|
||||
### 3. Filter by Agent
|
||||
|
||||
Use the agent filter dropdown to view spend for specific agents:
|
||||
|
||||
- Select one or more agent IDs from the dropdown
|
||||
- View filtered analytics, spend logs, and activity metrics
|
||||
- Compare spend across different agents
|
||||
|
||||
<Image img={require('../img/agent_usage_filter.png')} />
|
||||
|
||||
## Cost Configuration Options
|
||||
|
||||
You can mix and match these options depending on your pricing model:
|
||||
|
||||
| Field | Description |
|
||||
| ----------------------------- | ----------------------------------------- |
|
||||
| **Cost Per Query ($)** | Fixed cost charged for each agent request |
|
||||
| **Input Cost Per Token ($)** | Cost per input token processed |
|
||||
| **Output Cost Per Token ($)** | Cost per output token generated |
|
||||
|
||||
For most use cases, a flat cost per query is simplest. Use token-based pricing if your agent costs vary significantly based on input/output length.
|
||||
|
||||
## Related
|
||||
|
||||
- [A2A Agent Gateway](./a2a.md)
|
||||
- [Spend Tracking](./proxy/cost_tracking.md)
|
||||
373
docs/my-website/docs/adding_provider/generic_guardrail_api.md
Normal file
373
docs/my-website/docs/adding_provider/generic_guardrail_api.md
Normal file
|
|
@ -0,0 +1,373 @@
|
|||
# [BETA] Generic Guardrail API - Integrate Without a PR
|
||||
|
||||
## The Problem
|
||||
|
||||
As a guardrail provider, integrating with LiteLLM traditionally requires:
|
||||
- Making a PR to the LiteLLM repository
|
||||
- Waiting for review and merge
|
||||
- Maintaining provider-specific code in LiteLLM's codebase
|
||||
- Updating the integration for changes to your API
|
||||
|
||||
## The Solution
|
||||
|
||||
The **Generic Guardrail API** lets you integrate with LiteLLM **instantly** by implementing a simple API endpoint. No PR required.
|
||||
|
||||
### Key Benefits
|
||||
|
||||
1. **No PR Needed** - Deploy and integrate immediately
|
||||
2. **Universal Support** - Works across ALL LiteLLM endpoints (chat, embeddings, image generation, etc.)
|
||||
3. **Simple Contract** - One endpoint, three response types
|
||||
4. **Multi-Modal Support** - Handle both text and images in requests/responses
|
||||
5. **Custom Parameters** - Pass provider-specific params via config
|
||||
6. **Full Control** - You own and maintain your guardrail API
|
||||
|
||||
## Supported Endpoints
|
||||
|
||||
The Generic Guardrail API works with the following LiteLLM endpoints:
|
||||
|
||||
- `/v1/chat/completions` - OpenAI Chat Completions
|
||||
- `/v1/completions` - OpenAI Text Completions
|
||||
- `/v1/responses` - OpenAI Responses API
|
||||
- `/v1/images/generations` - OpenAI Image Generation
|
||||
- `/v1/audio/transcriptions` - OpenAI Audio Transcriptions
|
||||
- `/v1/audio/speech` - OpenAI Text-to-Speech
|
||||
- `/v1/messages` - Anthropic Messages
|
||||
- `/v1/rerank` - Cohere Rerank
|
||||
- Pass-through endpoints
|
||||
|
||||
## How It Works
|
||||
|
||||
1. LiteLLM extracts text and images from any request (chat messages, embeddings, image prompts, etc.)
|
||||
2. Sends extracted content + metadata to your API endpoint
|
||||
3. Your API responds with: `BLOCKED`, `NONE`, or `GUARDRAIL_INTERVENED`
|
||||
4. LiteLLM enforces the decision and applies any modifications
|
||||
|
||||
## API Contract
|
||||
|
||||
### Endpoint
|
||||
|
||||
Implement `POST /beta/litellm_basic_guardrail_api`
|
||||
|
||||
### Request Format
|
||||
|
||||
```json
|
||||
{
|
||||
"texts": ["extracted text from the request"], // array of text strings
|
||||
"images": ["base64_encoded_image_data"], // optional array of images
|
||||
"tools": [ // tool calls sent to the LLM (in the OpenAI Chat Completions spec)
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get the current weather",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {"type": "string"}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
],
|
||||
"tool_calls": [ // tool calls received from the LLM (in the OpenAI Chat Completions spec)
|
||||
{
|
||||
"id": "call_abc123",
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"arguments": "{\"location\": \"San Francisco\"}"
|
||||
}
|
||||
}
|
||||
],
|
||||
"structured_messages": [ // optional, full messages in OpenAI format (for chat endpoints)
|
||||
{"role": "system", "content": "You are a helpful assistant"},
|
||||
{"role": "user", "content": "Hello"}
|
||||
],
|
||||
"request_data": {
|
||||
"user_api_key_hash": "hash of the litellm virtual key used",
|
||||
"user_api_key_alias": "alias of the litellm virtual key used",
|
||||
"user_api_key_user_id": "user id associated with the litellm virtual key used",
|
||||
"user_api_key_user_email": "user email associated with the litellm virtual key used",
|
||||
"user_api_key_team_id": "team id associated with the litellm virtual key used",
|
||||
"user_api_key_team_alias": "team alias associated with the litellm virtual key used",
|
||||
"user_api_key_end_user_id": "end user id associated with the litellm virtual key used",
|
||||
"user_api_key_org_id": "org id associated with the litellm virtual key used"
|
||||
},
|
||||
"input_type": "request", // "request" or "response"
|
||||
"litellm_call_id": "unique_call_id", // the call id of the individual LLM call
|
||||
"litellm_trace_id": "trace_id", // the trace id of the LLM call - useful if there are multiple LLM calls for the same conversation
|
||||
"additional_provider_specific_params": {
|
||||
// your custom params from config
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Response Format
|
||||
|
||||
```json
|
||||
{
|
||||
"action": "BLOCKED" | "NONE" | "GUARDRAIL_INTERVENED",
|
||||
"blocked_reason": "why content was blocked", // required if action=BLOCKED
|
||||
"texts": ["modified text"], // optional array of modified text strings
|
||||
"images": ["modified_base64_image"] // optional array of modified images
|
||||
}
|
||||
```
|
||||
|
||||
**Actions:**
|
||||
- `BLOCKED` - LiteLLM raises error and blocks request
|
||||
- `NONE` - Request proceeds unchanged
|
||||
- `GUARDRAIL_INTERVENED` - Request proceeds with modified texts/images (provide `texts` and/or `images` fields)
|
||||
|
||||
## Parameters
|
||||
|
||||
### `tools` Parameter
|
||||
|
||||
The `tools` parameter provides information about available function/tool definitions in the request.
|
||||
|
||||
**Format:** OpenAI `ChatCompletionToolParam` format (see [OpenAI API reference](https://platform.openai.com/docs/api-reference/chat/create#chat-create-tools))
|
||||
|
||||
**Example:**
|
||||
```json
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get the current weather in a location",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {
|
||||
"type": "string",
|
||||
"description": "City and state, e.g. San Francisco, CA"
|
||||
},
|
||||
"unit": {
|
||||
"type": "string",
|
||||
"enum": ["celsius", "fahrenheit"]
|
||||
}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Availability:**
|
||||
- **Input only:** Tools are only passed for `input_type="request"` (pre-call guardrails). Output/response guardrails do not currently receive tool definitions.
|
||||
- **Supported endpoints:** The `tools` parameter is supported on: `/v1/chat/completions`, `/v1/responses`, and `/v1/messages`. Other endpoints do not have tool support.
|
||||
|
||||
**Use cases:**
|
||||
- Enforce tool permission policies (e.g., only allow certain users/teams to access specific tools)
|
||||
- Validate tool schemas before sending to LLM
|
||||
- Log tool usage for audit purposes
|
||||
- Block sensitive tools based on user context
|
||||
|
||||
### `tool_calls` Parameter
|
||||
|
||||
The `tool_calls` parameter contains actual function/tool invocations being made in the request or response.
|
||||
|
||||
**Format:** OpenAI `ChatCompletionMessageToolCall` format (see [OpenAI API reference](https://platform.openai.com/docs/api-reference/chat/object#chat/object-tool_calls))
|
||||
|
||||
**Example:**
|
||||
```json
|
||||
{
|
||||
"id": "call_abc123",
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"arguments": "{\"location\": \"San Francisco\", \"unit\": \"celsius\"}"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Key Difference from `tools`:**
|
||||
- **`tools`** = Tool definitions/schemas (what tools are *available*)
|
||||
- **`tool_calls`** = Tool invocations/executions (what tools are *being called* with what arguments)
|
||||
|
||||
**Availability:**
|
||||
- **Both input and output:** Tool calls can be present in both `input_type="request"` (assistant messages requesting tool calls) and `input_type="response"` (LLM responses with tool calls).
|
||||
- **Supported endpoints:** The `tool_calls` parameter is supported on: `/v1/chat/completions`, `/v1/responses`, and `/v1/messages`.
|
||||
|
||||
**Use cases:**
|
||||
- Validate tool call arguments before execution
|
||||
- Redact sensitive data from tool call arguments (e.g., PII)
|
||||
- Log tool invocations for audit/debugging
|
||||
- Block tool calls with dangerous parameters
|
||||
- Modify tool call arguments (e.g., enforce constraints, sanitize inputs)
|
||||
- Monitor tool usage patterns across users/teams
|
||||
|
||||
### `structured_messages` Parameter
|
||||
|
||||
The `structured_messages` parameter provides the full input in OpenAI chat completion spec format, useful for distinguishing between system and user messages.
|
||||
|
||||
**Format:** Array of OpenAI chat completion messages (see [OpenAI API reference](https://platform.openai.com/docs/api-reference/chat/create#chat-create-messages))
|
||||
|
||||
**Example:**
|
||||
```json
|
||||
[
|
||||
{"role": "system", "content": "You are a helpful assistant"},
|
||||
{"role": "user", "content": "Hello"}
|
||||
]
|
||||
```
|
||||
|
||||
**Availability:**
|
||||
- **Supported endpoints:** `/v1/chat/completions`, `/v1/messages`, `/v1/responses`
|
||||
- **Input only:** Only passed for `input_type="request"` (pre-call guardrails)
|
||||
|
||||
**Use cases:**
|
||||
- Apply different policies for system vs user messages
|
||||
- Enforce role-based content restrictions
|
||||
- Log structured conversation context
|
||||
|
||||
## LiteLLM Configuration
|
||||
|
||||
Add to `config.yaml`:
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
guardrails:
|
||||
- guardrail_name: "my-guardrail"
|
||||
litellm_params:
|
||||
guardrail: generic_guardrail_api
|
||||
mode: pre_call # or post_call, during_call
|
||||
api_base: https://your-guardrail-api.com
|
||||
api_key: os.environ/YOUR_GUARDRAIL_API_KEY # optional
|
||||
additional_provider_specific_params:
|
||||
# your custom parameters
|
||||
threshold: 0.8
|
||||
language: "en"
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
Users apply your guardrail by name:
|
||||
|
||||
```python
|
||||
response = client.chat.completions.create(
|
||||
model="gpt-4",
|
||||
messages=[{"role": "user", "content": "hello"}],
|
||||
guardrails=["my-guardrail"]
|
||||
)
|
||||
```
|
||||
|
||||
Or with dynamic parameters:
|
||||
|
||||
```python
|
||||
response = client.chat.completions.create(
|
||||
model="gpt-4",
|
||||
messages=[{"role": "user", "content": "hello"}],
|
||||
guardrails=[{
|
||||
"my-guardrail": {
|
||||
"extra_body": {
|
||||
"custom_threshold": 0.9
|
||||
}
|
||||
}
|
||||
}]
|
||||
)
|
||||
```
|
||||
|
||||
## Implementation Example
|
||||
|
||||
See [mock_bedrock_guardrail_server.py](https://github.com/BerriAI/litellm/blob/main/cookbook/mock_guardrail_server/mock_bedrock_guardrail_server.py) for a complete reference implementation.
|
||||
|
||||
**Minimal FastAPI example:**
|
||||
|
||||
```python
|
||||
from fastapi import FastAPI
|
||||
from pydantic import BaseModel
|
||||
from typing import List, Optional, Dict, Any
|
||||
|
||||
app = FastAPI()
|
||||
|
||||
class GuardrailRequest(BaseModel):
|
||||
texts: List[str]
|
||||
images: Optional[List[str]] = None
|
||||
tools: Optional[List[Dict[str, Any]]] = None # OpenAI ChatCompletionToolParam format (tool definitions)
|
||||
tool_calls: Optional[List[Dict[str, Any]]] = None # OpenAI ChatCompletionMessageToolCall format (tool invocations)
|
||||
structured_messages: Optional[List[Dict[str, Any]]] = None # OpenAI messages format (for chat endpoints)
|
||||
request_data: Dict[str, Any]
|
||||
input_type: str # "request" or "response"
|
||||
litellm_call_id: Optional[str] = None
|
||||
litellm_trace_id: Optional[str] = None
|
||||
additional_provider_specific_params: Dict[str, Any]
|
||||
|
||||
class GuardrailResponse(BaseModel):
|
||||
action: str # BLOCKED, NONE, or GUARDRAIL_INTERVENED
|
||||
blocked_reason: Optional[str] = None
|
||||
texts: Optional[List[str]] = None
|
||||
images: Optional[List[str]] = None
|
||||
|
||||
@app.post("/beta/litellm_basic_guardrail_api")
|
||||
async def apply_guardrail(request: GuardrailRequest):
|
||||
# Your guardrail logic here
|
||||
|
||||
# Example: Check text content
|
||||
for text in request.texts:
|
||||
if "badword" in text.lower():
|
||||
return GuardrailResponse(
|
||||
action="BLOCKED",
|
||||
blocked_reason="Content contains prohibited terms"
|
||||
)
|
||||
|
||||
# Example: Check tool definitions (if present in request)
|
||||
if request.tools:
|
||||
for tool in request.tools:
|
||||
if tool.get("type") == "function":
|
||||
function_name = tool.get("function", {}).get("name", "")
|
||||
# Block sensitive tool definitions
|
||||
if function_name in ["delete_data", "access_admin_panel"]:
|
||||
return GuardrailResponse(
|
||||
action="BLOCKED",
|
||||
blocked_reason=f"Tool '{function_name}' is not allowed"
|
||||
)
|
||||
|
||||
# Example: Check tool calls (if present in request or response)
|
||||
if request.tool_calls:
|
||||
for tool_call in request.tool_calls:
|
||||
if tool_call.get("type") == "function":
|
||||
function_name = tool_call.get("function", {}).get("name", "")
|
||||
arguments_str = tool_call.get("function", {}).get("arguments", "{}")
|
||||
|
||||
# Parse arguments and validate
|
||||
import json
|
||||
try:
|
||||
arguments = json.loads(arguments_str)
|
||||
# Block dangerous arguments
|
||||
if "file_path" in arguments and ".." in str(arguments["file_path"]):
|
||||
return GuardrailResponse(
|
||||
action="BLOCKED",
|
||||
blocked_reason="Tool call contains path traversal attempt"
|
||||
)
|
||||
except json.JSONDecodeError:
|
||||
pass
|
||||
|
||||
# Example: Check structured messages (if present in request)
|
||||
if request.structured_messages:
|
||||
for message in request.structured_messages:
|
||||
if message.get("role") == "system":
|
||||
# Apply stricter policies to system messages
|
||||
if "admin" in message.get("content", "").lower():
|
||||
return GuardrailResponse(
|
||||
action="BLOCKED",
|
||||
blocked_reason="System message contains restricted terms"
|
||||
)
|
||||
|
||||
return GuardrailResponse(action="NONE")
|
||||
```
|
||||
|
||||
## When to Use This
|
||||
|
||||
✅ **Use Generic Guardrail API when:**
|
||||
- You want instant integration without waiting for PRs
|
||||
- You maintain your own guardrail service
|
||||
- You need full control over updates and features
|
||||
- You want to support all LiteLLM endpoints automatically
|
||||
|
||||
❌ **Make a PR when:**
|
||||
- You want deeper integration with LiteLLM internals
|
||||
- Your guardrail requires complex LiteLLM-specific logic
|
||||
- You want to be featured as a built-in provider
|
||||
|
||||
## Questions?
|
||||
|
||||
This is a **beta API**. We're actively improving it based on feedback. Open an issue or PR if you need additional capabilities.
|
||||
|
||||
|
|
@ -37,57 +37,7 @@ Two files: `my_guardrail.py` (main class) and `__init__.py` (initialization).
|
|||
|
||||
`my_guardrail.py`:
|
||||
|
||||
```python
|
||||
import os
|
||||
from typing import Optional, List
|
||||
from fastapi import HTTPException
|
||||
|
||||
from litellm.integrations.custom_guardrail import CustomGuardrail
|
||||
from litellm.types.guardrails import PiiEntityType
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.llms.custom_httpx.http_handler import (
|
||||
get_async_httpx_client,
|
||||
httpxSpecialProvider,
|
||||
)
|
||||
|
||||
class MyGuardrail(CustomGuardrail):
|
||||
def __init__(self, api_key: Optional[str] = None, api_base: Optional[str] = None, **kwargs):
|
||||
self.api_key = api_key or os.getenv("MY_GUARDRAIL_API_KEY")
|
||||
self.api_base = api_base or os.getenv("MY_GUARDRAIL_API_BASE", "https://api.myguardrail.com")
|
||||
super().__init__(default_on=True)
|
||||
|
||||
async def apply_guardrail(
|
||||
self,
|
||||
text: str,
|
||||
language: Optional[str] = None,
|
||||
entities: Optional[List[PiiEntityType]] = None,
|
||||
request_data: Optional[dict] = None,
|
||||
) -> str:
|
||||
result = await self._check_with_api(text, request_data)
|
||||
|
||||
if result.get("action") == "BLOCK":
|
||||
raise Exception(f"Content blocked: {result.get('reason', 'Policy violation')}")
|
||||
|
||||
return text
|
||||
|
||||
async def _check_with_api(self, text: str, request_data: Optional[dict]) -> dict:
|
||||
async_client = get_async_httpx_client(llm_provider=httpxSpecialProvider.LoggingCallback)
|
||||
|
||||
headers = {
|
||||
"Content-Type": "application/json",
|
||||
"Authorization": f"Bearer {self.api_key}",
|
||||
}
|
||||
|
||||
response = await async_client.post(
|
||||
f"{self.api_base}/check",
|
||||
headers=headers,
|
||||
json={"text": text},
|
||||
timeout=5,
|
||||
)
|
||||
|
||||
response.raise_for_status()
|
||||
return response.json()
|
||||
```
|
||||
Follow from [Custom Guardrail](../proxy/guardrails/custom_guardrail#custom-guardrail) tutorial.
|
||||
|
||||
### Create the Init File
|
||||
|
||||
|
|
|
|||
231
docs/my-website/docs/anthropic_count_tokens.md
Normal file
231
docs/my-website/docs/anthropic_count_tokens.md
Normal file
|
|
@ -0,0 +1,231 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# /v1/messages/count_tokens
|
||||
|
||||
## Overview
|
||||
|
||||
Anthropic-compatible token counting endpoint. Count tokens for messages before sending them to the model.
|
||||
|
||||
| Feature | Supported | Notes |
|
||||
|---------|-----------|-------|
|
||||
| Cost Tracking | ❌ | Token counting only, no cost incurred |
|
||||
| Logging | ✅ | Works across all integrations |
|
||||
| End-user Tracking | ✅ | |
|
||||
| Supported Providers | Anthropic, Vertex AI (Claude), Bedrock (Claude), Gemini, Vertex AI | Auto-routes to provider-specific token counting APIs |
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Start LiteLLM Proxy
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
### 2. Count Tokens
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="curl" label="curl">
|
||||
|
||||
```bash
|
||||
curl -X POST "http://localhost:4000/v1/messages/count_tokens" \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "claude-3-5-sonnet-20241022",
|
||||
"messages": [
|
||||
{"role": "user", "content": "Hello, how are you?"}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="python" label="Python (httpx)">
|
||||
|
||||
```python
|
||||
import httpx
|
||||
|
||||
response = httpx.post(
|
||||
"http://localhost:4000/v1/messages/count_tokens",
|
||||
headers={
|
||||
"Content-Type": "application/json",
|
||||
"Authorization": "Bearer sk-1234"
|
||||
},
|
||||
json={
|
||||
"model": "claude-3-5-sonnet-20241022",
|
||||
"messages": [
|
||||
{"role": "user", "content": "Hello, how are you?"}
|
||||
]
|
||||
}
|
||||
)
|
||||
|
||||
print(response.json())
|
||||
# {"input_tokens": 14}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
**Expected Response:**
|
||||
|
||||
```json
|
||||
{
|
||||
"input_tokens": 14
|
||||
}
|
||||
```
|
||||
|
||||
## LiteLLM Proxy Configuration
|
||||
|
||||
Add models to your `config.yaml`:
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-3-5-sonnet
|
||||
litellm_params:
|
||||
model: anthropic/claude-3-5-sonnet-20241022
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
|
||||
- model_name: claude-vertex
|
||||
litellm_params:
|
||||
model: vertex_ai/claude-3-5-sonnet-v2@20241022
|
||||
vertex_project: my-project
|
||||
vertex_location: us-east5
|
||||
|
||||
- model_name: claude-bedrock
|
||||
litellm_params:
|
||||
model: bedrock/anthropic.claude-3-5-sonnet-20241022-v2:0
|
||||
aws_region_name: us-west-2
|
||||
```
|
||||
|
||||
## Request Parameters
|
||||
|
||||
| Parameter | Type | Required | Description |
|
||||
|-----------|------|----------|-------------|
|
||||
| `model` | string | ✅ | The model to use for token counting |
|
||||
| `messages` | array | ✅ | Array of messages in Anthropic format |
|
||||
|
||||
### Messages Format
|
||||
|
||||
```json
|
||||
{
|
||||
"messages": [
|
||||
{"role": "user", "content": "Hello!"},
|
||||
{"role": "assistant", "content": "Hi there!"},
|
||||
{"role": "user", "content": "How are you?"}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
## Response Format
|
||||
|
||||
```json
|
||||
{
|
||||
"input_tokens": <number>
|
||||
}
|
||||
```
|
||||
|
||||
| Field | Type | Description |
|
||||
|-------|------|-------------|
|
||||
| `input_tokens` | integer | Number of tokens in the input messages |
|
||||
|
||||
## Supported Providers
|
||||
|
||||
The `/v1/messages/count_tokens` endpoint automatically routes to the appropriate provider-specific token counting API:
|
||||
|
||||
| Provider | Token Counting Method |
|
||||
|----------|----------------------|
|
||||
| Anthropic | [Anthropic Token Counting API](https://docs.anthropic.com/en/docs/build-with-claude/token-counting) |
|
||||
| Vertex AI (Claude) | Vertex AI Partner Models Token Counter |
|
||||
| Bedrock (Claude) | AWS Bedrock CountTokens API |
|
||||
| Gemini | Google AI Studio countTokens API |
|
||||
| Vertex AI (Gemini) | Vertex AI countTokens API |
|
||||
|
||||
## Examples
|
||||
|
||||
### Count Tokens with System Message
|
||||
|
||||
```bash
|
||||
curl -X POST "http://localhost:4000/v1/messages/count_tokens" \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "claude-3-5-sonnet-20241022",
|
||||
"messages": [
|
||||
{"role": "user", "content": "You are a helpful assistant. Please help me write a haiku about programming."}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
### Count Tokens for Multi-turn Conversation
|
||||
|
||||
```bash
|
||||
curl -X POST "http://localhost:4000/v1/messages/count_tokens" \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "claude-3-5-sonnet-20241022",
|
||||
"messages": [
|
||||
{"role": "user", "content": "What is the capital of France?"},
|
||||
{"role": "assistant", "content": "The capital of France is Paris."},
|
||||
{"role": "user", "content": "What is its population?"}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
### Using with Vertex AI Claude
|
||||
|
||||
```bash
|
||||
curl -X POST "http://localhost:4000/v1/messages/count_tokens" \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "claude-vertex",
|
||||
"messages": [
|
||||
{"role": "user", "content": "Hello, world!"}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
### Using with Bedrock Claude
|
||||
|
||||
```bash
|
||||
curl -X POST "http://localhost:4000/v1/messages/count_tokens" \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "claude-bedrock",
|
||||
"messages": [
|
||||
{"role": "user", "content": "Hello, world!"}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
## Comparison with Anthropic Passthrough
|
||||
|
||||
LiteLLM provides two ways to count tokens:
|
||||
|
||||
| Endpoint | Description | Use Case |
|
||||
|----------|-------------|----------|
|
||||
| `/v1/messages/count_tokens` | LiteLLM's Anthropic-compatible endpoint | Works with all supported providers (Anthropic, Vertex AI, Bedrock, etc.) |
|
||||
| `/anthropic/v1/messages/count_tokens` | [Pass-through to Anthropic API](./pass_through/anthropic_completion.md#example-2-token-counting-api) | Direct Anthropic API access with native headers |
|
||||
|
||||
### Pass-through Example
|
||||
|
||||
For direct Anthropic API access with full native headers:
|
||||
|
||||
```bash
|
||||
curl --request POST \
|
||||
--url http://0.0.0.0:4000/anthropic/v1/messages/count_tokens \
|
||||
--header "x-api-key: $LITELLM_API_KEY" \
|
||||
--header "anthropic-version: 2023-06-01" \
|
||||
--header "anthropic-beta: token-counting-2024-11-01" \
|
||||
--header "content-type: application/json" \
|
||||
--data '{
|
||||
"model": "claude-3-5-sonnet-20241022",
|
||||
"messages": [
|
||||
{"role": "user", "content": "Hello, world"}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
|
@ -3,6 +3,14 @@ import TabItem from '@theme/TabItem';
|
|||
|
||||
# /assistants
|
||||
|
||||
:::warning Deprecation Notice
|
||||
|
||||
OpenAI has deprecated the Assistants API. It will shut down on **August 26, 2026**.
|
||||
|
||||
Consider migrating to the [Responses API](/docs/response_api) instead. See [OpenAI's migration guide](https://platform.openai.com/docs/guides/responses-vs-assistants) for details.
|
||||
|
||||
:::
|
||||
|
||||
Covers Threads, Messages, Assistants.
|
||||
|
||||
LiteLLM currently covers:
|
||||
|
|
|
|||
|
|
@ -13,7 +13,7 @@ import TabItem from '@theme/TabItem';
|
|||
| Fallbacks | ✅ | Works between supported models |
|
||||
| Loadbalancing | ✅ | Works between supported models |
|
||||
| Guardrails | ✅ | Applies to output transcribed text (non-streaming only) |
|
||||
| Supported Providers | `openai`, `azure`, `vertex_ai`, `gemini`, `deepgram`, `groq`, `fireworks_ai` | |
|
||||
| Supported Providers | `openai`, `azure`, `vertex_ai`, `gemini`, `deepgram`, `groq`, `fireworks_ai`, `ovhcloud` | |
|
||||
|
||||
## Quick Start
|
||||
|
||||
|
|
@ -126,6 +126,7 @@ transcript = client.audio.transcriptions.create(
|
|||
- [Fireworks AI](./providers/fireworks_ai.md#audio-transcription)
|
||||
- [Groq](./providers/groq.md#speech-to-text---whisper)
|
||||
- [Deepgram](./providers/deepgram.md)
|
||||
- [OVHcloud AI Endpoints](./providers/ovhcloud.md)
|
||||
|
||||
---
|
||||
|
||||
|
|
|
|||
|
|
@ -174,6 +174,257 @@ print("list_batches_response=", list_batches_response)
|
|||
</Tabs>
|
||||
|
||||
|
||||
## Multi-Account / Model-Based Routing
|
||||
|
||||
Route batch operations to different provider accounts using model-specific credentials from your `config.yaml`. This eliminates the need for environment variables and enables multi-tenant batch processing.
|
||||
|
||||
### How It Works
|
||||
|
||||
**Priority Order:**
|
||||
1. **Encoded Batch/File ID** (highest) - Model info embedded in the ID
|
||||
2. **Model Parameter** - Via header (`x-litellm-model`), query param, or request body
|
||||
3. **Custom Provider** (fallback) - Uses environment variables
|
||||
|
||||
### Configuration
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-4o-account-1
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
api_key: sk-account-1-key
|
||||
api_base: https://api.openai.com/v1
|
||||
|
||||
- model_name: gpt-4o-account-2
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
api_key: sk-account-2-key
|
||||
api_base: https://api.openai.com/v1
|
||||
|
||||
- model_name: azure-batches
|
||||
litellm_params:
|
||||
model: azure/gpt-4
|
||||
api_key: azure-key-123
|
||||
api_base: https://my-resource.openai.azure.com
|
||||
api_version: "2024-02-01"
|
||||
```
|
||||
|
||||
### Usage Examples
|
||||
|
||||
#### Scenario 1: Encoded File ID with Model
|
||||
|
||||
When you upload a file with a model parameter, LiteLLM encodes the model information in the file ID. All subsequent operations automatically use those credentials.
|
||||
|
||||
```bash
|
||||
# Step 1: Upload file with model
|
||||
curl http://localhost:4000/v1/files \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "x-litellm-model: gpt-4o-account-1" \
|
||||
-F purpose="batch" \
|
||||
-F file="@batch.jsonl"
|
||||
|
||||
# Response includes encoded file ID:
|
||||
# {
|
||||
# "id": "file-bGl0ZWxsbTpmaWxlLUxkaUwzaVYxNGZRVlpYcU5KVEdkSjk7bW9kZWwsZ3B0LTRvLWFjY291bnQtMQ",
|
||||
# ...
|
||||
# }
|
||||
|
||||
# Step 2: Create batch - automatically routes to gpt-4o-account-1
|
||||
curl http://localhost:4000/v1/batches \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"input_file_id": "file-bGl0ZWxsbTpmaWxlLUxkaUwzaVYxNGZRVlpYcU5KVEdkSjk7bW9kZWwsZ3B0LTRvLWFjY291bnQtMQ",
|
||||
"endpoint": "/v1/chat/completions",
|
||||
"completion_window": "24h"
|
||||
}'
|
||||
|
||||
# Batch ID is also encoded with model:
|
||||
# {
|
||||
# "id": "batch_bGl0ZWxsbTpiYXRjaF82OTIwM2IzNjg0MDQ4MTkwYTA3ODQ5NDY3YTFjMDJkYTttb2RlbCxncHQtNG8tYWNjb3VudC0x",
|
||||
# "input_file_id": "file-bGl0ZWxsbTpmaWxlLUxkaUwzaVYxNGZRVlpYcU5KVEdkSjk7bW9kZWwsZ3B0LTRvLWFjY291bnQtMQ",
|
||||
# ...
|
||||
# }
|
||||
|
||||
# Step 3: Retrieve batch - automatically routes to gpt-4o-account-1
|
||||
curl http://localhost:4000/v1/batches/batch_bGl0ZWxsbTpiYXRjaF82OTIwM2IzNjg0MDQ4MTkwYTA3ODQ5NDY3YTFjMDJkYTttb2RlbCxncHQtNG8tYWNjb3VudC0x \
|
||||
-H "Authorization: Bearer sk-1234"
|
||||
```
|
||||
|
||||
**✅ Benefits:**
|
||||
- No need to specify model on every request
|
||||
- File and batch IDs "remember" which account created them
|
||||
- Automatic routing for retrieve, cancel, and file content operations
|
||||
|
||||
#### Scenario 2: Model via Header/Query Parameter
|
||||
|
||||
Specify the model for each request without encoding it in the ID.
|
||||
|
||||
```bash
|
||||
# Create batch with model header
|
||||
curl http://localhost:4000/v1/batches \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "x-litellm-model: gpt-4o-account-2" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"input_file_id": "file-abc123",
|
||||
"endpoint": "/v1/chat/completions",
|
||||
"completion_window": "24h"
|
||||
}'
|
||||
|
||||
# Or use query parameter
|
||||
curl "http://localhost:4000/v1/batches?model=gpt-4o-account-2" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"input_file_id": "file-abc123",
|
||||
"endpoint": "/v1/chat/completions",
|
||||
"completion_window": "24h"
|
||||
}'
|
||||
|
||||
# List batches for specific model
|
||||
curl "http://localhost:4000/v1/batches?model=gpt-4o-account-2" \
|
||||
-H "Authorization: Bearer sk-1234"
|
||||
```
|
||||
|
||||
**✅ Use Case:**
|
||||
- One-off batch operations
|
||||
- Different models for different operations
|
||||
- Explicit control over routing
|
||||
|
||||
#### Scenario 3: Environment Variables (Fallback)
|
||||
|
||||
Traditional approach using environment variables when no model is specified.
|
||||
|
||||
```bash
|
||||
export OPENAI_API_KEY="sk-env-key"
|
||||
|
||||
curl http://localhost:4000/v1/batches \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"input_file_id": "file-abc123",
|
||||
"endpoint": "/v1/chat/completions",
|
||||
"completion_window": "24h"
|
||||
}'
|
||||
```
|
||||
|
||||
**✅ Use Case:**
|
||||
- Backward compatibility
|
||||
- Simple single-account setups
|
||||
- Quick prototyping
|
||||
|
||||
### Complete Multi-Account Example
|
||||
|
||||
```bash
|
||||
# Upload file to Account 1
|
||||
FILE_1=$(curl -s http://localhost:4000/v1/files \
|
||||
-H "x-litellm-model: gpt-4o-account-1" \
|
||||
-F purpose="batch" \
|
||||
-F file="@batch1.jsonl" | jq -r '.id')
|
||||
|
||||
# Upload file to Account 2
|
||||
FILE_2=$(curl -s http://localhost:4000/v1/files \
|
||||
-H "x-litellm-model: gpt-4o-account-2" \
|
||||
-F purpose="batch" \
|
||||
-F file="@batch2.jsonl" | jq -r '.id')
|
||||
|
||||
# Create batch on Account 1 (auto-routed via encoded file ID)
|
||||
BATCH_1=$(curl -s http://localhost:4000/v1/batches \
|
||||
-d "{\"input_file_id\": \"$FILE_1\", \"endpoint\": \"/v1/chat/completions\", \"completion_window\": \"24h\"}" | jq -r '.id')
|
||||
|
||||
# Create batch on Account 2 (auto-routed via encoded file ID)
|
||||
BATCH_2=$(curl -s http://localhost:4000/v1/batches \
|
||||
-d "{\"input_file_id\": \"$FILE_2\", \"endpoint\": \"/v1/chat/completions\", \"completion_window\": \"24h\"}" | jq -r '.id')
|
||||
|
||||
# Retrieve both batches (auto-routed to correct accounts)
|
||||
curl http://localhost:4000/v1/batches/$BATCH_1
|
||||
curl http://localhost:4000/v1/batches/$BATCH_2
|
||||
|
||||
# List batches per account
|
||||
curl "http://localhost:4000/v1/batches?model=gpt-4o-account-1"
|
||||
curl "http://localhost:4000/v1/batches?model=gpt-4o-account-2"
|
||||
```
|
||||
|
||||
### SDK Usage with Model Routing
|
||||
|
||||
```python
|
||||
import litellm
|
||||
import asyncio
|
||||
|
||||
# Upload file with model routing
|
||||
file_obj = await litellm.acreate_file(
|
||||
file=open("batch.jsonl", "rb"),
|
||||
purpose="batch",
|
||||
model="gpt-4o-account-1", # Route to specific account
|
||||
)
|
||||
|
||||
print(f"File ID: {file_obj.id}")
|
||||
# File ID is encoded with model info
|
||||
|
||||
# Create batch - automatically uses gpt-4o-account-1 credentials
|
||||
batch = await litellm.acreate_batch(
|
||||
completion_window="24h",
|
||||
endpoint="/v1/chat/completions",
|
||||
input_file_id=file_obj.id, # Model info embedded in ID
|
||||
)
|
||||
|
||||
print(f"Batch ID: {batch.id}")
|
||||
# Batch ID is also encoded
|
||||
|
||||
# Retrieve batch - automatically routes to correct account
|
||||
retrieved = await litellm.aretrieve_batch(
|
||||
batch_id=batch.id, # Model info embedded in ID
|
||||
)
|
||||
|
||||
print(f"Batch status: {retrieved.status}")
|
||||
|
||||
# Or explicitly specify model
|
||||
batch2 = await litellm.acreate_batch(
|
||||
completion_window="24h",
|
||||
endpoint="/v1/chat/completions",
|
||||
input_file_id="file-regular-id",
|
||||
model="gpt-4o-account-2", # Explicit routing
|
||||
)
|
||||
```
|
||||
|
||||
### How ID Encoding Works
|
||||
|
||||
LiteLLM encodes model information into file and batch IDs using base64:
|
||||
|
||||
```
|
||||
Original: file-abc123
|
||||
Encoded: file-bGl0ZWxsbTpmaWxlLWFiYzEyMzttb2RlbCxncHQtNG8tdGVzdA
|
||||
└─┬─┘ └──────────────────┬──────────────────────┘
|
||||
prefix base64(litellm:file-abc123;model,gpt-4o-test)
|
||||
|
||||
Original: batch_xyz789
|
||||
Encoded: batch_bGl0ZWxsbTpiYXRjaF94eXo3ODk7bW9kZWwsZ3B0LTRvLXRlc3Q
|
||||
└──┬──┘ └──────────────────┬──────────────────────┘
|
||||
prefix base64(litellm:batch_xyz789;model,gpt-4o-test)
|
||||
```
|
||||
|
||||
The encoding:
|
||||
- ✅ Preserves OpenAI-compatible prefixes (`file-`, `batch_`)
|
||||
- ✅ Is transparent to clients
|
||||
- ✅ Enables automatic routing without additional parameters
|
||||
- ✅ Works across all batch and file endpoints
|
||||
|
||||
### Supported Endpoints
|
||||
|
||||
All batch and file endpoints support model-based routing:
|
||||
|
||||
| Endpoint | Method | Model Routing |
|
||||
|----------|--------|---------------|
|
||||
| `/v1/files` | POST | ✅ Via header/query/body |
|
||||
| `/v1/files/{file_id}` | GET | ✅ Auto from encoded ID + header/query |
|
||||
| `/v1/files/{file_id}/content` | GET | ✅ Auto from encoded ID + header/query |
|
||||
| `/v1/files/{file_id}` | DELETE | ✅ Auto from encoded ID |
|
||||
| `/v1/batches` | POST | ✅ Auto from file ID + header/query/body |
|
||||
| `/v1/batches` | GET | ✅ Via header/query |
|
||||
| `/v1/batches/{batch_id}` | GET | ✅ Auto from encoded ID |
|
||||
| `/v1/batches/{batch_id}/cancel` | POST | ✅ Auto from encoded ID |
|
||||
|
||||
## **Supported Providers**:
|
||||
### [Azure OpenAI](./providers/azure#azure-batches-api)
|
||||
### [OpenAI](#quick-start)
|
||||
|
|
|
|||
|
|
@ -125,18 +125,23 @@ class MyUser(HttpUser):
|
|||
## LiteLLM vs Portkey Performance Comparison
|
||||
|
||||
**Test Configuration**: 4 CPUs, 8 GB RAM per instance | Load: 1k concurrent users, 500 ramp-up
|
||||
**Versions:** Portkey **v1.14.0** | LiteLLM **v1.79.1-stable**
|
||||
**Test Duration:** 5 minutes
|
||||
|
||||
### Multi-Instance (4×) Performance
|
||||
|
||||
| Metric | Portkey (no DB) | LiteLLM (with DB) |
|
||||
| ------------------- | --------------- | ----------------- |
|
||||
| **Total Requests** | 293,796 | 312,405 |
|
||||
| **Failed Requests** | 0 | 0 |
|
||||
| **Median Latency** | 100 ms | 100 ms |
|
||||
| **p95 Latency** | 230 ms | 150 ms |
|
||||
| **p99 Latency** | 500 ms | 240 ms |
|
||||
| **Average Latency** | 123 ms | 111 ms |
|
||||
| **Current RPS** | 1,170.9 | 1,170 |
|
||||
| Metric | Portkey (no DB) | LiteLLM (with DB) | Comment |
|
||||
| ------------------- | --------------- | ----------------- | -------------- |
|
||||
| **Total Requests** | 293,796 | 312,405 | LiteLLM higher |
|
||||
| **Failed Requests** | 0 | 0 | Same |
|
||||
| **Median Latency** | 100 ms | 100 ms | Same |
|
||||
| **p95 Latency** | 230 ms | 150 ms | LiteLLM lower |
|
||||
| **p99 Latency** | 500 ms | 240 ms | LiteLLM lower |
|
||||
| **Average Latency** | 123 ms | 111 ms | LiteLLM lower |
|
||||
| **Current RPS** | 1,170.9 | 1,170 | Same |
|
||||
|
||||
|
||||
*Lower is better for latency metrics; higher is better for requests and RPS.*
|
||||
|
||||
### Technical Insights
|
||||
|
||||
|
|
|
|||
|
|
@ -5,6 +5,14 @@ import TabItem from '@theme/TabItem';
|
|||
|
||||
Drop unsupported OpenAI params by your LLM Provider.
|
||||
|
||||
## Default Behavior
|
||||
|
||||
**By default, LiteLLM raises an exception** if you send a parameter to a model that doesn't support it.
|
||||
|
||||
For example, if you send `temperature=0.2` to a model that doesn't support the `temperature` parameter, LiteLLM will raise an exception.
|
||||
|
||||
**When `drop_params=True` is set**, LiteLLM will drop the unsupported parameter instead of raising an exception. This allows your code to work seamlessly across different providers without having to customize parameters for each one.
|
||||
|
||||
## Quick Start
|
||||
|
||||
```python
|
||||
|
|
@ -109,6 +117,56 @@ response = litellm.completion(
|
|||
|
||||
**additional_drop_params**: List or null - Is a list of openai params you want to drop when making a call to the model.
|
||||
|
||||
### Nested Field Removal
|
||||
|
||||
Drop nested fields within complex objects using JSONPath-like notation:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="bedrock/us.anthropic.claude-sonnet-4-5-20250929-v1:0",
|
||||
messages=[{"role": "user", "content": "Hello"}],
|
||||
tools=[{
|
||||
"name": "search",
|
||||
"description": "Search files",
|
||||
"input_schema": {"type": "object", "properties": {"query": {"type": "string"}}},
|
||||
"input_examples": [{"query": "test"}] # Will be removed
|
||||
}],
|
||||
additional_drop_params=["tools[*].input_examples"] # Remove from all tools
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: my-bedrock-model
|
||||
litellm_params:
|
||||
model: bedrock/us.anthropic.claude-sonnet-4-5-20250929-v1:0
|
||||
additional_drop_params: ["tools[*].input_examples"] # Remove from all tools
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
**Supported syntax:**
|
||||
- `field` - Top-level field
|
||||
- `parent.child` - Nested object field
|
||||
- `array[*]` - All array elements
|
||||
- `array[0]` - Specific array index
|
||||
- `tools[*].input_examples` - Field in all array elements
|
||||
- `tools[0].metadata.field` - Specific index + nested field
|
||||
|
||||
**Example use cases:**
|
||||
- Remove `input_examples` from tool definitions (Claude Code + AWS Bedrock)
|
||||
- Drop provider-specific fields from nested structures
|
||||
- Clean up nested parameters before sending to LLM
|
||||
|
||||
## Specify allowed openai params in a request
|
||||
|
||||
Tell litellm to allow specific openai params in a request. Use this if you get a `litellm.UnsupportedParamsError` and want to allow a param. LiteLLM will pass the param as is to the model.
|
||||
|
|
|
|||
|
|
@ -224,8 +224,8 @@ asyncio.run(generate_image())
|
|||
|
||||
| Provider | Model |
|
||||
|----------|--------|
|
||||
| Google AI Studio | `gemini/gemini-2.0-flash-preview-image-generation`, `gemini/gemini-2.5-flash-image-preview` |
|
||||
| Vertex AI | `vertex_ai/gemini-2.0-flash-preview-image-generation`, `vertex_ai/gemini-2.5-flash-image-preview` |
|
||||
| Google AI Studio | `gemini/gemini-2.0-flash-preview-image-generation`, `gemini/gemini-2.5-flash-image-preview`, `gemini/gemini-3-pro-image-preview` |
|
||||
| Vertex AI | `vertex_ai/gemini-2.0-flash-preview-image-generation`, `vertex_ai/gemini-2.5-flash-image-preview`, `vertex_ai/gemini-3-pro-image-preview` |
|
||||
|
||||
## Spec
|
||||
|
||||
|
|
|
|||
|
|
@ -174,11 +174,11 @@ def completion(
|
|||
|
||||
- `seed`: *integer or null (optional)* - This feature is in Beta. If specified, our system will make a best effort to sample deterministically, such that repeated requests with the same seed and parameters should return the same result. Determinism is not guaranteed, and you should refer to the `system_fingerprint` response parameter to monitor changes in the backend.
|
||||
|
||||
- `tools`: *array (optional)* - A list of tools the model may call. Currently, only functions are supported as a tool. Use this to provide a list of functions the model may generate JSON inputs for.
|
||||
- `tools`: *array (optional)* - A list of tools the model may call. Use this to provide a list of functions the model may generate JSON inputs for.
|
||||
|
||||
- `type`: *string* - The type of the tool. Currently, only function is supported.
|
||||
- `type`: *string* - The type of the tool. You can set this to `"function"` or `"mcp"` (matching the `/responses` schema) to call LiteLLM-registered MCP servers directly from `/chat/completions`.
|
||||
|
||||
- `function`: *object* - Required.
|
||||
- `function`: *object* - Required for function tools.
|
||||
|
||||
- `tool_choice`: *string or object (optional)* - Controls which (if any) function is called by the model. none means the model will not call a function and instead generates a message. auto means the model can pick between generating a message or calling a function. Specifying a particular function via `{"type": "function", "function": {"name": "my_function"}}` forces the model to call that function.
|
||||
|
||||
|
|
@ -247,4 +247,3 @@ def completion(
|
|||
- `eos_token`: *string (optional)* - Initial string applied at the end of a sequence
|
||||
|
||||
- `hf_model_name`: *string (optional)* - [Sagemaker Only] The corresponding huggingface name of the model, used to pull the right chat template for the model.
|
||||
|
||||
|
|
|
|||
|
|
@ -126,6 +126,8 @@ resp = completion(
|
|||
)
|
||||
|
||||
print("Received={}".format(resp))
|
||||
|
||||
events_list = EventsList.model_validate_json(resp.choices[0].message.content)
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
|
|
|||
|
|
@ -18,8 +18,11 @@ LiteLLM integrates with vector stores, allowing your models to access your organ
|
|||
## Supported Vector Stores
|
||||
- [Bedrock Knowledge Bases](https://aws.amazon.com/bedrock/knowledge-bases/)
|
||||
- [OpenAI Vector Stores](https://platform.openai.com/docs/api-reference/vector-stores/search)
|
||||
- [Azure Vector Stores](https://learn.microsoft.com/en-us/azure/ai-services/openai/how-to/file-search?tabs=python#vector-stores) (Cannot be directly queried. Only available for calling in Assistants messages. We will be adding Azure AI Search Vector Store API support soon.)
|
||||
- [Azure Vector Stores](https://learn.microsoft.com/en-us/azure/ai-services/openai/how-to/file-search?tabs=python#vector-stores) (Cannot be directly queried. Only available for calling in Assistants messages.)
|
||||
- [Azure AI Search](/docs/providers/azure_ai_vector_stores) (Vector search with Azure AI Search indexes)
|
||||
- [Vertex AI RAG API](https://cloud.google.com/vertex-ai/generative-ai/docs/rag-overview)
|
||||
- [Gemini File Search](https://ai.google.dev/gemini-api/docs/file-search)
|
||||
- [RAGFlow Datasets](/docs/providers/ragflow_vector_store.md) (Dataset management only, search not supported)
|
||||
|
||||
## Quick Start
|
||||
|
||||
|
|
|
|||
|
|
@ -31,7 +31,7 @@ response = completion(
|
|||
{
|
||||
"type": "image_url",
|
||||
"image_url": {
|
||||
"url": "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg"
|
||||
"url": "https://awsmp-logos.s3.amazonaws.com/seller-xw5kijmvmzasy/c233c9ade2ccb5491072ae232c814942.png"
|
||||
}
|
||||
}
|
||||
]
|
||||
|
|
@ -92,7 +92,7 @@ response = client.chat.completions.create(
|
|||
{
|
||||
"type": "image_url",
|
||||
"image_url": {
|
||||
"url": "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg"
|
||||
"url": "https://awsmp-logos.s3.amazonaws.com/seller-xw5kijmvmzasy/c233c9ade2ccb5491072ae232c814942.png"
|
||||
}
|
||||
}
|
||||
]
|
||||
|
|
@ -230,7 +230,7 @@ response = completion(
|
|||
{
|
||||
"type": "image_url",
|
||||
"image_url": {
|
||||
"url": "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg",
|
||||
"url": "https://awsmp-logos.s3.amazonaws.com/seller-xw5kijmvmzasy/c233c9ade2ccb5491072ae232c814942.png",
|
||||
"format": "image/jpeg"
|
||||
}
|
||||
}
|
||||
|
|
@ -292,7 +292,7 @@ response = client.chat.completions.create(
|
|||
{
|
||||
"type": "image_url",
|
||||
"image_url": {
|
||||
"url": "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg",
|
||||
"url": "https://awsmp-logos.s3.amazonaws.com/seller-xw5kijmvmzasy/c233c9ade2ccb5491072ae232c814942.png",
|
||||
"format": "image/jpeg"
|
||||
}
|
||||
}
|
||||
|
|
|
|||
|
|
@ -371,6 +371,22 @@ model_list:
|
|||
web_search_options: {} # Enables web search with default settings
|
||||
```
|
||||
|
||||
### Advanced
|
||||
You can configure LiteLLM's router to optionally drop models that do not support WebSearch, for example
|
||||
```yaml
|
||||
- model_name: gpt-4.1
|
||||
litellm_params:
|
||||
model: openai/gpt-4.1
|
||||
- model_name: gpt-4.1
|
||||
litellm_params:
|
||||
model: azure/gpt-4.1
|
||||
api_base: "x.openai.azure.com/"
|
||||
api_version: 2025-03-01-preview
|
||||
model_info:
|
||||
supports_web_search: False <---- KEY CHANGE!
|
||||
```
|
||||
In this example, LiteLLM will still route LLM requests to both deployments, but for WebSearch, will solely route to OpenAI.
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="custom" label="Custom Search Context">
|
||||
|
||||
|
|
|
|||
303
docs/my-website/docs/container_files.md
Normal file
303
docs/my-website/docs/container_files.md
Normal file
|
|
@ -0,0 +1,303 @@
|
|||
---
|
||||
id: container_files
|
||||
title: /containers/files
|
||||
---
|
||||
|
||||
# Container Files API
|
||||
|
||||
Manage files within Code Interpreter containers. Files are created automatically when code interpreter generates outputs (charts, CSVs, images, etc.).
|
||||
|
||||
:::tip
|
||||
Looking for how to use Code Interpreter? See the [Code Interpreter Guide](/docs/guides/code_interpreter).
|
||||
:::
|
||||
|
||||
| Feature | Supported |
|
||||
|---------|-----------|
|
||||
| Cost Tracking | ✅ |
|
||||
| Logging | ✅ |
|
||||
| Supported Providers | `openai` |
|
||||
|
||||
## Endpoints
|
||||
|
||||
| Endpoint | Method | Description |
|
||||
|----------|--------|-------------|
|
||||
| `/v1/containers/{container_id}/files` | GET | List files in container |
|
||||
| `/v1/containers/{container_id}/files/{file_id}` | GET | Get file metadata |
|
||||
| `/v1/containers/{container_id}/files/{file_id}/content` | GET | Download file content |
|
||||
| `/v1/containers/{container_id}/files/{file_id}` | DELETE | Delete file |
|
||||
|
||||
## LiteLLM Python SDK
|
||||
|
||||
### List Container Files
|
||||
|
||||
```python showLineNumbers title="list_container_files.py"
|
||||
from litellm import list_container_files
|
||||
|
||||
files = list_container_files(
|
||||
container_id="cntr_123...",
|
||||
custom_llm_provider="openai"
|
||||
)
|
||||
|
||||
for file in files.data:
|
||||
print(f" - {file.id}: {file.filename}")
|
||||
```
|
||||
|
||||
**Async:**
|
||||
|
||||
```python showLineNumbers title="alist_container_files.py"
|
||||
from litellm import alist_container_files
|
||||
|
||||
files = await alist_container_files(
|
||||
container_id="cntr_123...",
|
||||
custom_llm_provider="openai"
|
||||
)
|
||||
```
|
||||
|
||||
### Retrieve Container File
|
||||
|
||||
```python showLineNumbers title="retrieve_container_file.py"
|
||||
from litellm import retrieve_container_file
|
||||
|
||||
file = retrieve_container_file(
|
||||
container_id="cntr_123...",
|
||||
file_id="cfile_456...",
|
||||
custom_llm_provider="openai"
|
||||
)
|
||||
|
||||
print(f"File: {file.filename}")
|
||||
print(f"Size: {file.bytes} bytes")
|
||||
```
|
||||
|
||||
### Download File Content
|
||||
|
||||
```python showLineNumbers title="retrieve_container_file_content.py"
|
||||
from litellm import retrieve_container_file_content
|
||||
|
||||
content = retrieve_container_file_content(
|
||||
container_id="cntr_123...",
|
||||
file_id="cfile_456...",
|
||||
custom_llm_provider="openai"
|
||||
)
|
||||
|
||||
# content is raw bytes
|
||||
with open("output.png", "wb") as f:
|
||||
f.write(content)
|
||||
```
|
||||
|
||||
### Delete Container File
|
||||
|
||||
```python showLineNumbers title="delete_container_file.py"
|
||||
from litellm import delete_container_file
|
||||
|
||||
result = delete_container_file(
|
||||
container_id="cntr_123...",
|
||||
file_id="cfile_456...",
|
||||
custom_llm_provider="openai"
|
||||
)
|
||||
|
||||
print(f"Deleted: {result.deleted}")
|
||||
```
|
||||
|
||||
## LiteLLM AI Gateway (Proxy)
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
### List Files
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="openai-sdk" label="OpenAI SDK">
|
||||
|
||||
```python showLineNumbers title="list_files.py"
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
api_key="sk-1234",
|
||||
base_url="http://localhost:4000"
|
||||
)
|
||||
|
||||
files = client.containers.files.list(
|
||||
container_id="cntr_123..."
|
||||
)
|
||||
|
||||
for file in files.data:
|
||||
print(f" - {file.id}: {file.filename}")
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="curl" label="curl">
|
||||
|
||||
```bash showLineNumbers title="list_files.sh"
|
||||
curl "http://localhost:4000/v1/containers/cntr_123.../files" \
|
||||
-H "Authorization: Bearer sk-1234"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Retrieve File Metadata
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="openai-sdk" label="OpenAI SDK">
|
||||
|
||||
```python showLineNumbers title="retrieve_file.py"
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
api_key="sk-1234",
|
||||
base_url="http://localhost:4000"
|
||||
)
|
||||
|
||||
file = client.containers.files.retrieve(
|
||||
container_id="cntr_123...",
|
||||
file_id="cfile_456..."
|
||||
)
|
||||
|
||||
print(f"File: {file.filename}")
|
||||
print(f"Size: {file.bytes} bytes")
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="curl" label="curl">
|
||||
|
||||
```bash showLineNumbers title="retrieve_file.sh"
|
||||
curl "http://localhost:4000/v1/containers/cntr_123.../files/cfile_456..." \
|
||||
-H "Authorization: Bearer sk-1234"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Download File Content
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="openai-sdk" label="OpenAI SDK">
|
||||
|
||||
```python showLineNumbers title="download_content.py"
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
api_key="sk-1234",
|
||||
base_url="http://localhost:4000"
|
||||
)
|
||||
|
||||
content = client.containers.files.content(
|
||||
container_id="cntr_123...",
|
||||
file_id="cfile_456..."
|
||||
)
|
||||
|
||||
with open("output.png", "wb") as f:
|
||||
f.write(content.read())
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="curl" label="curl">
|
||||
|
||||
```bash showLineNumbers title="download_content.sh"
|
||||
curl "http://localhost:4000/v1/containers/cntr_123.../files/cfile_456.../content" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
--output downloaded_file.png
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Delete File
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="openai-sdk" label="OpenAI SDK">
|
||||
|
||||
```python showLineNumbers title="delete_file.py"
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
api_key="sk-1234",
|
||||
base_url="http://localhost:4000"
|
||||
)
|
||||
|
||||
result = client.containers.files.delete(
|
||||
container_id="cntr_123...",
|
||||
file_id="cfile_456..."
|
||||
)
|
||||
|
||||
print(f"Deleted: {result.deleted}")
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="curl" label="curl">
|
||||
|
||||
```bash showLineNumbers title="delete_file.sh"
|
||||
curl -X DELETE "http://localhost:4000/v1/containers/cntr_123.../files/cfile_456..." \
|
||||
-H "Authorization: Bearer sk-1234"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Parameters
|
||||
|
||||
### List Files
|
||||
|
||||
| Parameter | Type | Required | Description |
|
||||
|-----------|------|----------|-------------|
|
||||
| `container_id` | string | Yes | Container ID |
|
||||
| `after` | string | No | Pagination cursor |
|
||||
| `limit` | integer | No | Items to return (1-100, default: 20) |
|
||||
| `order` | string | No | Sort order: `asc` or `desc` |
|
||||
|
||||
### Retrieve/Delete File
|
||||
|
||||
| Parameter | Type | Required | Description |
|
||||
|-----------|------|----------|-------------|
|
||||
| `container_id` | string | Yes | Container ID |
|
||||
| `file_id` | string | Yes | File ID |
|
||||
|
||||
## Response Objects
|
||||
|
||||
### ContainerFileObject
|
||||
|
||||
```json showLineNumbers title="ContainerFileObject"
|
||||
{
|
||||
"id": "cfile_456...",
|
||||
"object": "container.file",
|
||||
"container_id": "cntr_123...",
|
||||
"bytes": 12345,
|
||||
"created_at": 1234567890,
|
||||
"filename": "chart.png",
|
||||
"path": "/mnt/data/chart.png",
|
||||
"source": "code_interpreter"
|
||||
}
|
||||
```
|
||||
|
||||
### ContainerFileListResponse
|
||||
|
||||
```json showLineNumbers title="ContainerFileListResponse"
|
||||
{
|
||||
"object": "list",
|
||||
"data": [...],
|
||||
"first_id": "cfile_456...",
|
||||
"last_id": "cfile_789...",
|
||||
"has_more": false
|
||||
}
|
||||
```
|
||||
|
||||
### DeleteContainerFileResponse
|
||||
|
||||
```json showLineNumbers title="DeleteContainerFileResponse"
|
||||
{
|
||||
"id": "cfile_456...",
|
||||
"object": "container.file.deleted",
|
||||
"deleted": true
|
||||
}
|
||||
```
|
||||
|
||||
## Supported Providers
|
||||
|
||||
| Provider | Status |
|
||||
|----------|--------|
|
||||
| OpenAI | ✅ Supported |
|
||||
|
||||
## Related
|
||||
|
||||
- [Containers API](/docs/containers) - Manage containers
|
||||
- [Code Interpreter Guide](/docs/guides/code_interpreter) - Using Code Interpreter with LiteLLM
|
||||
|
|
@ -2,6 +2,10 @@
|
|||
|
||||
Manage OpenAI code interpreter containers (sessions) for executing code in isolated environments.
|
||||
|
||||
:::tip
|
||||
Looking for how to use Code Interpreter? See the [Code Interpreter Guide](/docs/guides/code_interpreter).
|
||||
:::
|
||||
|
||||
| Feature | Supported |
|
||||
|---------|-----------|
|
||||
| Cost Tracking | ✅ |
|
||||
|
|
@ -463,3 +467,8 @@ Currently, only OpenAI supports container management for code interpreter sessio
|
|||
|
||||
:::
|
||||
|
||||
## Related
|
||||
|
||||
- [Container Files API](/docs/container_files) - Manage files within containers
|
||||
- [Code Interpreter Guide](/docs/guides/code_interpreter) - Using Code Interpreter with LiteLLM
|
||||
|
||||
|
|
|
|||
|
|
@ -0,0 +1,114 @@
|
|||
# Contribute Custom Webhook API
|
||||
|
||||
If your API just needs a Webhook event from LiteLLM, here's how to add a 'native' integration for it on LiteLLM:
|
||||
|
||||
1. Clone the repo and open the `generic_api_compatible_callbacks.json`
|
||||
|
||||
```bash
|
||||
git clone https://github.com/BerriAI/litellm.git
|
||||
cd litellm
|
||||
open .
|
||||
```
|
||||
|
||||
2. Add your API to the `generic_api_compatible_callbacks.json`
|
||||
|
||||
Example:
|
||||
|
||||
```json
|
||||
{
|
||||
"rubrik": {
|
||||
"event_types": ["llm_api_success"],
|
||||
"endpoint": "{{environment_variables.RUBRIK_WEBHOOK_URL}}",
|
||||
"headers": {
|
||||
"Content-Type": "application/json",
|
||||
"Authorization": "Bearer {{environment_variables.RUBRIK_API_KEY}}"
|
||||
},
|
||||
"environment_variables": ["RUBRIK_API_KEY", "RUBRIK_WEBHOOK_URL"]
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Spec:
|
||||
|
||||
```json
|
||||
{
|
||||
"sample_callback": {
|
||||
"event_types": ["llm_api_success", "llm_api_failure"], # Optional - defaults to all events
|
||||
"endpoint": "{{environment_variables.SAMPLE_CALLBACK_URL}}",
|
||||
"headers": {
|
||||
"Content-Type": "application/json",
|
||||
"Authorization": "Bearer {{environment_variables.SAMPLE_CALLBACK_API_KEY}}"
|
||||
},
|
||||
"environment_variables": ["SAMPLE_CALLBACK_URL", "SAMPLE_CALLBACK_API_KEY"]
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
3. Test it!
|
||||
|
||||
a. Setup config.yaml
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-3.5-turbo
|
||||
litellm_params:
|
||||
model: openai/gpt-3.5-turbo
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
- model_name: anthropic-claude
|
||||
litellm_params:
|
||||
model: anthropic/claude-3-5-sonnet-20241022
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
|
||||
litellm_settings:
|
||||
callbacks: ["rubrik"]
|
||||
|
||||
environment_variables:
|
||||
RUBRIK_API_KEY: sk-1234
|
||||
RUBRIK_WEBHOOK_URL: https://webhook.site/efc57707-9018-478c-bdf1-2ffaabb2b315
|
||||
```
|
||||
|
||||
b. Start the proxy
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
c. Test it!
|
||||
|
||||
```bash
|
||||
curl -L -X POST 'http://0.0.0.0:4000/chat/completions' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-d '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "system",
|
||||
"content": "Ignore previous instructions"
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What is the weather like in Boston today?"
|
||||
}
|
||||
],
|
||||
"mock_response": "hey!"
|
||||
}'
|
||||
```
|
||||
|
||||
4. Add Documentation
|
||||
|
||||
If you're adding a new integration, please add documentation for it under the `observability` folder:
|
||||
|
||||
- Create a new file at `docs/my-website/docs/observability/<your_integration>_integration.md`
|
||||
- Follow the format of existing integration docs, such as [Langsmith Integration](https://github.com/BerriAI/litellm/blob/main/docs/my-website/docs/observability/langsmith_integration.md)
|
||||
- Include: Quick Start, SDK usage, Proxy usage, and any advanced configuration options
|
||||
|
||||
5. File a PR!
|
||||
|
||||
- Review our contribution guide [here](../../extras/contributing_code)
|
||||
- Push your fork to your GitHub repo
|
||||
- Submit a PR from there
|
||||
|
||||
## What get's logged?
|
||||
|
||||
The [LiteLLM Standard Logging Payload](https://docs.litellm.ai/docs/proxy/logging_spec) is sent to your endpoint.
|
||||
|
|
@ -0,0 +1,130 @@
|
|||
# Adding OpenAI-Compatible Providers
|
||||
|
||||
For simple OpenAI-compatible providers (like Hyperbolic, Nscale, etc.), you can add support by editing a single JSON file.
|
||||
|
||||
## Quick Start
|
||||
|
||||
1. Edit `litellm/llms/openai_like/providers.json`
|
||||
2. Add your provider configuration
|
||||
3. Test with: `litellm.completion(model="your_provider/model-name", ...)`
|
||||
|
||||
## Basic Configuration
|
||||
|
||||
For a fully OpenAI-compatible provider:
|
||||
|
||||
```json
|
||||
{
|
||||
"your_provider": {
|
||||
"base_url": "https://api.yourprovider.com/v1",
|
||||
"api_key_env": "YOUR_PROVIDER_API_KEY"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
That's it! The provider is now available.
|
||||
|
||||
## Configuration Options
|
||||
|
||||
### Required Fields
|
||||
|
||||
- `base_url` - API endpoint (e.g., `https://api.provider.com/v1`)
|
||||
- `api_key_env` - Environment variable name for API key (e.g., `PROVIDER_API_KEY`)
|
||||
|
||||
### Optional Fields
|
||||
|
||||
- `api_base_env` - Environment variable to override `base_url`
|
||||
- `base_class` - Use `"openai_gpt"` (default) or `"openai_like"`
|
||||
- `param_mappings` - Map OpenAI parameter names to provider-specific names
|
||||
- `constraints` - Parameter value constraints (min/max)
|
||||
- `special_handling` - Special behaviors like content format conversion
|
||||
|
||||
## Examples
|
||||
|
||||
### Simple Provider (Fully Compatible)
|
||||
|
||||
```json
|
||||
{
|
||||
"hyperbolic": {
|
||||
"base_url": "https://api.hyperbolic.xyz/v1",
|
||||
"api_key_env": "HYPERBOLIC_API_KEY"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Provider with Parameter Mapping
|
||||
|
||||
```json
|
||||
{
|
||||
"publicai": {
|
||||
"base_url": "https://api.publicai.co/v1",
|
||||
"api_key_env": "PUBLICAI_API_KEY",
|
||||
"param_mappings": {
|
||||
"max_completion_tokens": "max_tokens"
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Provider with Constraints
|
||||
|
||||
```json
|
||||
{
|
||||
"custom_provider": {
|
||||
"base_url": "https://api.custom.com/v1",
|
||||
"api_key_env": "CUSTOM_API_KEY",
|
||||
"constraints": {
|
||||
"temperature_max": 1.0,
|
||||
"temperature_min": 0.0
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
```python
|
||||
import litellm
|
||||
import os
|
||||
|
||||
# Set your API key
|
||||
os.environ["YOUR_PROVIDER_API_KEY"] = "your-key-here"
|
||||
|
||||
# Use the provider
|
||||
response = litellm.completion(
|
||||
model="your_provider/model-name",
|
||||
messages=[{"role": "user", "content": "Hello"}],
|
||||
)
|
||||
```
|
||||
|
||||
## When to Use Python Instead
|
||||
|
||||
Use a Python config class if you need:
|
||||
|
||||
- Custom authentication flows (OAuth, JWT, etc.)
|
||||
- Complex request/response transformations
|
||||
- Provider-specific streaming logic
|
||||
- Advanced tool calling modifications
|
||||
|
||||
For these cases, create a config class in `litellm/llms/your_provider/chat/transformation.py` that inherits from `OpenAIGPTConfig` or `OpenAILikeChatConfig`.
|
||||
|
||||
## Testing
|
||||
|
||||
Test your provider:
|
||||
|
||||
```bash
|
||||
# Quick test
|
||||
python -c "
|
||||
import litellm
|
||||
import os
|
||||
os.environ['PROVIDER_API_KEY'] = 'your-key'
|
||||
response = litellm.completion(
|
||||
model='provider/model-name',
|
||||
messages=[{'role': 'user', 'content': 'test'}]
|
||||
)
|
||||
print(response.choices[0].message.content)
|
||||
"
|
||||
```
|
||||
|
||||
## Reference
|
||||
|
||||
See existing providers in `litellm/llms/openai_like/providers.json` for examples.
|
||||
|
|
@ -10,6 +10,26 @@ import os
|
|||
os.environ['OPENAI_API_KEY'] = ""
|
||||
response = embedding(model='text-embedding-ada-002', input=["good morning from litellm"])
|
||||
```
|
||||
|
||||
## Async Usage - `aembedding()`
|
||||
|
||||
LiteLLM provides an asynchronous version of the `embedding` function called `aembedding`:
|
||||
|
||||
```python
|
||||
from litellm import aembedding
|
||||
import asyncio
|
||||
|
||||
async def get_embedding():
|
||||
response = await aembedding(
|
||||
model='text-embedding-ada-002',
|
||||
input=["good morning from litellm"]
|
||||
)
|
||||
return response
|
||||
|
||||
response = asyncio.run(get_embedding())
|
||||
print(response)
|
||||
```
|
||||
|
||||
## Proxy Usage
|
||||
|
||||
**NOTE**
|
||||
|
|
@ -263,6 +283,8 @@ print(response)
|
|||
|
||||
| Model Name | Function Call |
|
||||
|----------------------|---------------------------------------------|
|
||||
| Amazon Nova Multimodal Embeddings | `embedding(model="bedrock/amazon.nova-2-multimodal-embeddings-v1:0", input=input)` | [Nova Docs](../providers/bedrock_embedding#amazon-nova-multimodal-embeddings) |
|
||||
| Amazon Nova (Async) | `embedding(model="bedrock/async_invoke/amazon.nova-2-multimodal-embeddings-v1:0", input=input, input_type="text", output_s3_uri="s3://bucket/")` | [Nova Async Docs](../providers/bedrock_embedding#asynchronous-embeddings-with-segmentation) |
|
||||
| Titan Embeddings - G1 | `embedding(model="amazon.titan-embed-text-v1", input=input)` |
|
||||
| Cohere Embeddings - English | `embedding(model="cohere.embed-english-v3", input=input)` |
|
||||
| Cohere Embeddings - Multilingual | `embedding(model="cohere.embed-multilingual-v3", input=input)` |
|
||||
|
|
|
|||
|
|
@ -3,7 +3,8 @@ import Image from '@theme/IdealImage';
|
|||
# Enterprise
|
||||
|
||||
:::info
|
||||
✨ SSO is free for up to 5 users. After that, an enterprise license is required. [Get Started with Enterprise here](https://www.litellm.ai/enterprise)
|
||||
- ✨ SSO is free for up to 5 users. After that, an enterprise license is required. [Get Started with Enterprise here](https://www.litellm.ai/enterprise)
|
||||
- Who is Enterprise for? Companies giving access to 100+ users **OR** 10+ AI use-cases. If you're not sure, [get in touch with us](https://calendly.com/d/4mp-gd3-k5k/litellm-1-1-onboarding-chat) to discuss your needs.
|
||||
:::
|
||||
|
||||
For companies that need SSO, user management and professional support for LiteLLM Proxy
|
||||
|
|
@ -16,7 +17,7 @@ Get free 7-day trial key [here](https://www.litellm.ai/enterprise#trial)
|
|||
|
||||
Includes all enterprise features.
|
||||
|
||||
<Image img={require('../img/enterprise_vs_oss.png')} />
|
||||
<Image img={require('../img/enterprise_vs_oss_2.png')} />
|
||||
|
||||
[**Procurement available via AWS / Azure Marketplace**](./data_security.md#legalcompliance-faqs)
|
||||
|
||||
|
|
@ -40,7 +41,7 @@ Self-Managed Enterprise deployments require our team to understand your exact ne
|
|||
|
||||
### How does deployment with Enterprise License work?
|
||||
|
||||
You just deploy [our docker image](https://docs.litellm.ai/docs/proxy/deploy) and get an enterprise license key to add to your environment to unlock additional functionality (SSO, Prometheus metrics, etc.).
|
||||
You just deploy [our docker image](https://docs.litellm.ai/docs/proxy/deploy) and get an enterprise license key to add to your environment to unlock additional functionality (SSO, etc.).
|
||||
|
||||
```env
|
||||
LITELLM_LICENSE="eyJ..."
|
||||
|
|
|
|||
|
|
@ -107,3 +107,18 @@ docker run \
|
|||
litellm_test_image \
|
||||
--config /app/config.yaml --detailed_debug
|
||||
```
|
||||
### Running LiteLLM Proxy Locally
|
||||
|
||||
1. cd into the `proxy/` directory
|
||||
|
||||
```
|
||||
cd litellm/litellm/proxy
|
||||
```
|
||||
|
||||
2. Run the proxy
|
||||
|
||||
```shell
|
||||
python3 proxy_cli.py --config /path/to/config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
|
@ -16,7 +16,137 @@ Use this to call the provider's `/files` endpoints directly, in the OpenAI forma
|
|||
- Delete File
|
||||
- Get File Content
|
||||
|
||||
## Multi-Account Support (Multiple OpenAI Keys)
|
||||
|
||||
Use different OpenAI API keys for files and batches by specifying a `model` parameter that references entries in your `model_list`. This approach works **without requiring a database** and allows you to route files/batches to different OpenAI accounts.
|
||||
|
||||
### How It Works
|
||||
|
||||
1. Define models in `model_list` with different API keys
|
||||
2. Pass `model` parameter when creating files
|
||||
3. LiteLLM returns encoded IDs that contain routing information
|
||||
4. Use encoded IDs for all subsequent operations (retrieve, delete, batches)
|
||||
5. No need to specify model again - routing info is in the ID
|
||||
|
||||
### Setup
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
# litellm OpenAI Account
|
||||
- model_name: "gpt-4o-litellm"
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
api_key: os.environ/OPENAI_LITELLM_API_KEY
|
||||
|
||||
# Free OpenAI Account
|
||||
- model_name: "gpt-4o-free"
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
api_key: os.environ/OPENAI_FREE_API_KEY
|
||||
```
|
||||
|
||||
### Usage Example
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
api_key="sk-1234", # Your LiteLLM proxy key
|
||||
base_url="http://0.0.0.0:4000"
|
||||
)
|
||||
|
||||
# Create file using litellm account
|
||||
file_response = client.files.create(
|
||||
file=open("batch_data.jsonl", "rb"),
|
||||
purpose="batch",
|
||||
extra_body={"model": "gpt-4o-litellm"} # Routes to litellm key
|
||||
)
|
||||
print(f"File ID: {file_response.id}")
|
||||
# Returns encoded ID like: file-bGl0ZWxsbTpmaWxlLWFiYzEyMzttb2RlbCxncHQtNG8taWZvb2Q
|
||||
|
||||
# Create batch using the encoded file ID
|
||||
# No need to specify model again - it's embedded in the file ID
|
||||
batch_response = client.batches.create(
|
||||
input_file_id=file_response.id, # Encoded ID
|
||||
endpoint="/v1/chat/completions",
|
||||
completion_window="24h"
|
||||
)
|
||||
print(f"Batch ID: {batch_response.id}")
|
||||
# Returns encoded batch ID with routing info
|
||||
|
||||
# Retrieve batch - routing happens automatically
|
||||
batch_status = client.batches.retrieve(batch_response.id)
|
||||
print(f"Status: {batch_status.status}")
|
||||
|
||||
# List files for a specific account
|
||||
files = client.files.list(
|
||||
extra_body={"model": "gpt-4o-free"} # List free files
|
||||
)
|
||||
|
||||
# List batches for a specific account
|
||||
batches = client.batches.list(
|
||||
extra_query={"model": "gpt-4o-litellm"} # List litellm batches
|
||||
)
|
||||
```
|
||||
|
||||
### Parameter Options
|
||||
|
||||
You can pass the `model` parameter via:
|
||||
- **Request body**: `extra_body={"model": "gpt-4o-litellm"}`
|
||||
- **Query parameter**: `?model=gpt-4o-litellm`
|
||||
- **Header**: `x-litellm-model: gpt-4o-litellm`
|
||||
|
||||
### How Encoded IDs Work
|
||||
|
||||
- When you create a file/batch with a `model` parameter, LiteLLM encodes the model name into the returned ID
|
||||
- The encoded ID is base64-encoded and looks like: `file-bGl0ZWxsbTpmaWxlLWFiYzEyMzttb2RlbCxncHQtNG8taWZvb2Q`
|
||||
- When you use this ID in subsequent operations (retrieve, delete, batch create), LiteLLM automatically:
|
||||
1. Decodes the ID
|
||||
2. Extracts the model name
|
||||
3. Looks up the credentials
|
||||
4. Routes the request to the correct OpenAI account
|
||||
- The original provider file/batch ID is preserved internally
|
||||
|
||||
### Benefits
|
||||
|
||||
✅ **No Database Required** - All routing info stored in the ID
|
||||
✅ **Stateless** - Works across proxy restarts
|
||||
✅ **Simple** - Just pass the ID around like normal
|
||||
✅ **Backward Compatible** - Existing `custom_llm_provider` and `files_settings` still work
|
||||
✅ **Future-Proof** - Aligns with managed batches approach
|
||||
|
||||
### Migration from files_settings
|
||||
|
||||
**Old approach (still works):**
|
||||
```yaml
|
||||
files_settings:
|
||||
- custom_llm_provider: openai
|
||||
api_key: os.environ/OPENAI_KEY
|
||||
```
|
||||
|
||||
```python
|
||||
# Had to specify provider on every call
|
||||
client.files.create(..., extra_headers={"custom-llm-provider": "openai"})
|
||||
client.files.retrieve(file_id, extra_headers={"custom-llm-provider": "openai"})
|
||||
```
|
||||
|
||||
**New approach (recommended):**
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: "gpt-4o-account1"
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
api_key: os.environ/OPENAI_KEY
|
||||
```
|
||||
|
||||
```python
|
||||
# Specify model once on create
|
||||
file = client.files.create(..., extra_body={"model": "gpt-4o-account1"})
|
||||
|
||||
# Then just use the ID - routing is automatic
|
||||
client.files.retrieve(file.id) # No need to specify account
|
||||
client.batches.create(input_file_id=file.id) # Routes correctly
|
||||
```
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM PROXY Server">
|
||||
|
|
@ -171,6 +301,17 @@ content = await litellm.afile_content(
|
|||
print("file content=", content)
|
||||
```
|
||||
|
||||
**Get File Content (Bedrock)**
|
||||
```python
|
||||
# For Bedrock batch output files stored in S3
|
||||
content = await litellm.afile_content(
|
||||
file_id="s3://bucket-name/path/to/file.jsonl", # S3 URI or unified file ID
|
||||
custom_llm_provider="bedrock",
|
||||
aws_region_name="us-west-2"
|
||||
)
|
||||
print("file content=", content.text)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
|
@ -183,4 +324,6 @@ print("file content=", content)
|
|||
|
||||
### [Vertex AI](./providers/vertex#batch-apis)
|
||||
|
||||
### [Bedrock](./providers/bedrock_batches#4-retrieve-batch-results)
|
||||
|
||||
## [Swagger API Reference](https://litellm-api.up.railway.app/#/files)
|
||||
|
|
|
|||
|
|
@ -1,108 +0,0 @@
|
|||
# Getting Started
|
||||
|
||||
import QuickStart from '../src/components/QuickStart.js'
|
||||
|
||||
LiteLLM simplifies LLM API calls by mapping them all to the [OpenAI ChatCompletion format](https://platform.openai.com/docs/api-reference/chat).
|
||||
|
||||
## basic usage
|
||||
|
||||
By default we provide a free $10 community-key to try all providers supported on LiteLLM.
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
## set ENV variables
|
||||
os.environ["OPENAI_API_KEY"] = "your-api-key"
|
||||
os.environ["COHERE_API_KEY"] = "your-api-key"
|
||||
|
||||
messages = [{ "content": "Hello, how are you?","role": "user"}]
|
||||
|
||||
# openai call
|
||||
response = completion(model="gpt-3.5-turbo", messages=messages)
|
||||
|
||||
# cohere call
|
||||
response = completion("command-nightly", messages)
|
||||
```
|
||||
|
||||
**Need a dedicated key?**
|
||||
Email us @ krrish@berri.ai
|
||||
|
||||
Next Steps 👉 [Call all supported models - e.g. Claude-2, Llama2-70b, etc.](./proxy_api.md#supported-models)
|
||||
|
||||
More details 👉
|
||||
|
||||
- [Completion() function details](./completion/)
|
||||
- [Overview of supported models / providers on LiteLLM](./providers/)
|
||||
- [Search all models / providers](https://models.litellm.ai/)
|
||||
- [Build your own OpenAI proxy](https://github.com/BerriAI/liteLLM-proxy/tree/main)
|
||||
|
||||
## streaming
|
||||
|
||||
Same example from before. Just pass in `stream=True` in the completion args.
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
## set ENV variables
|
||||
os.environ["OPENAI_API_KEY"] = "openai key"
|
||||
os.environ["COHERE_API_KEY"] = "cohere key"
|
||||
|
||||
messages = [{ "content": "Hello, how are you?","role": "user"}]
|
||||
|
||||
# openai call
|
||||
response = completion(model="gpt-3.5-turbo", messages=messages, stream=True)
|
||||
|
||||
# cohere call
|
||||
response = completion("command-nightly", messages, stream=True)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
More details 👉
|
||||
|
||||
- [streaming + async](./completion/stream.md)
|
||||
- [tutorial for streaming Llama2 on TogetherAI](./tutorials/TogetherAI_liteLLM.md)
|
||||
|
||||
## exception handling
|
||||
|
||||
LiteLLM maps exceptions across all supported providers to the OpenAI exceptions. All our exceptions inherit from OpenAI's exception types, so any error-handling you have for that, should work out of the box with LiteLLM.
|
||||
|
||||
```python
|
||||
from openai.error import OpenAIError
|
||||
from litellm import completion
|
||||
|
||||
os.environ["ANTHROPIC_API_KEY"] = "bad-key"
|
||||
try:
|
||||
# some code
|
||||
completion(model="claude-instant-1", messages=[{"role": "user", "content": "Hey, how's it going?"}])
|
||||
except OpenAIError as e:
|
||||
print(e)
|
||||
```
|
||||
|
||||
## Logging Observability - Log LLM Input/Output ([Docs](https://docs.litellm.ai/docs/observability/callbacks))
|
||||
|
||||
LiteLLM exposes pre defined callbacks to send data to MLflow, Lunary, Langfuse, Helicone, Promptlayer, Traceloop, Slack
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
## set env variables for logging tools (API key set up is not required when using MLflow)
|
||||
os.environ["LUNARY_PUBLIC_KEY"] = "your-lunary-public-key" # get your public key at https://app.lunary.ai/settings
|
||||
os.environ["HELICONE_API_KEY"] = "your-helicone-key"
|
||||
os.environ["LANGFUSE_PUBLIC_KEY"] = ""
|
||||
os.environ["LANGFUSE_SECRET_KEY"] = ""
|
||||
|
||||
os.environ["OPENAI_API_KEY"]
|
||||
|
||||
# set callbacks
|
||||
litellm.success_callback = ["lunary", "mlflow", "langfuse", "helicone"] # log input/output to MLflow, langfuse, lunary, helicone
|
||||
|
||||
#openai call
|
||||
response = completion(model="gpt-3.5-turbo", messages=[{"role": "user", "content": "Hi 👋 - i'm openai"}])
|
||||
```
|
||||
|
||||
More details 👉
|
||||
|
||||
- [exception mapping](./exception_mapping.md)
|
||||
- [retries + model fallbacks for completion()](./completion/reliable_completions.md)
|
||||
- [tutorial for model fallbacks with completion()](./tutorials/fallbacks.md)
|
||||
168
docs/my-website/docs/guides/code_interpreter.md
Normal file
168
docs/my-website/docs/guides/code_interpreter.md
Normal file
|
|
@ -0,0 +1,168 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Code Interpreter
|
||||
|
||||
Use OpenAI's Code Interpreter tool to execute Python code in a secure, sandboxed environment.
|
||||
|
||||
| Feature | Supported |
|
||||
|---------|-----------|
|
||||
| LiteLLM Python SDK | ✅ |
|
||||
| LiteLLM AI Gateway | ✅ |
|
||||
| Supported Providers | `openai` |
|
||||
|
||||
## LiteLLM AI Gateway
|
||||
|
||||
### API (OpenAI SDK)
|
||||
|
||||
Use the OpenAI SDK pointed at your LiteLLM Gateway:
|
||||
|
||||
```python showLineNumbers title="code_interpreter_gateway.py"
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
api_key="sk-1234", # Your LiteLLM API key
|
||||
base_url="http://localhost:4000"
|
||||
)
|
||||
|
||||
response = client.responses.create(
|
||||
model="openai/gpt-4o",
|
||||
tools=[{"type": "code_interpreter"}],
|
||||
input="Calculate the first 20 fibonacci numbers and plot them"
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
#### Streaming
|
||||
|
||||
```python showLineNumbers title="code_interpreter_streaming.py"
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
api_key="sk-1234",
|
||||
base_url="http://localhost:4000"
|
||||
)
|
||||
|
||||
stream = client.responses.create(
|
||||
model="openai/gpt-4o",
|
||||
tools=[{"type": "code_interpreter"}],
|
||||
input="Generate sample sales data CSV and create a visualization",
|
||||
stream=True
|
||||
)
|
||||
|
||||
for event in stream:
|
||||
print(event)
|
||||
```
|
||||
|
||||
#### Get Generated File Content
|
||||
|
||||
```python showLineNumbers title="get_file_content_gateway.py"
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
api_key="sk-1234",
|
||||
base_url="http://localhost:4000"
|
||||
)
|
||||
|
||||
# 1. Run code interpreter
|
||||
response = client.responses.create(
|
||||
model="openai/gpt-4o",
|
||||
tools=[{"type": "code_interpreter"}],
|
||||
input="Create a scatter plot and save as PNG"
|
||||
)
|
||||
|
||||
# 2. Get container_id from response
|
||||
container_id = response.output[0].container_id
|
||||
|
||||
# 3. List files
|
||||
files = client.containers.files.list(container_id=container_id)
|
||||
|
||||
# 4. Download file content
|
||||
for file in files.data:
|
||||
content = client.containers.files.content(
|
||||
container_id=container_id,
|
||||
file_id=file.id
|
||||
)
|
||||
|
||||
with open(file.filename, "wb") as f:
|
||||
f.write(content.read())
|
||||
print(f"Downloaded: {file.filename}")
|
||||
```
|
||||
|
||||
### AI Gateway UI
|
||||
|
||||
The LiteLLM Admin UI includes built-in Code Interpreter support.
|
||||
|
||||
<Image img={require('../../img/code_interp.png')} />
|
||||
|
||||
**Steps:**
|
||||
|
||||
1. Go to **Playground** in the LiteLLM UI
|
||||
2. Select an **OpenAI model** (e.g., `openai/gpt-4o`)
|
||||
3. Select `/v1/responses` as the endpoint under **Endpoint Type**
|
||||
4. Toggle **Code Interpreter** in the left panel
|
||||
5. Send a prompt requesting code execution or file generation
|
||||
|
||||
The UI will display:
|
||||
- Executed Python code (collapsible)
|
||||
- Generated images inline
|
||||
- Download links for files (CSVs, etc.)
|
||||
|
||||
## LiteLLM Python SDK
|
||||
|
||||
### Run Code Interpreter
|
||||
|
||||
```python showLineNumbers title="code_interpreter.py"
|
||||
import litellm
|
||||
|
||||
response = litellm.responses(
|
||||
model="openai/gpt-4o",
|
||||
input="Generate a bar chart of quarterly sales and save as PNG",
|
||||
tools=[{"type": "code_interpreter"}]
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
### Get Generated File Content
|
||||
|
||||
After Code Interpreter runs, retrieve the generated files:
|
||||
|
||||
```python showLineNumbers title="get_file_content.py"
|
||||
import litellm
|
||||
|
||||
# 1. Run code interpreter
|
||||
response = litellm.responses(
|
||||
model="openai/gpt-4o",
|
||||
input="Create a pie chart of market share and save as PNG",
|
||||
tools=[{"type": "code_interpreter"}]
|
||||
)
|
||||
|
||||
# 2. Extract container_id from response
|
||||
container_id = response.output[0].container_id # e.g. "cntr_abc123..."
|
||||
|
||||
# 3. List files in container
|
||||
files = litellm.list_container_files(
|
||||
container_id=container_id,
|
||||
custom_llm_provider="openai"
|
||||
)
|
||||
|
||||
# 4. Download each file
|
||||
for file in files.data:
|
||||
content = litellm.retrieve_container_file_content(
|
||||
container_id=container_id,
|
||||
file_id=file.id,
|
||||
custom_llm_provider="openai"
|
||||
)
|
||||
|
||||
with open(file.filename, "wb") as f:
|
||||
f.write(content)
|
||||
print(f"Downloaded: {file.filename}")
|
||||
```
|
||||
|
||||
|
||||
## Related
|
||||
|
||||
- [Containers API](/docs/containers) - Manage containers
|
||||
- [Container Files API](/docs/container_files) - Manage files within containers
|
||||
- [OpenAI Code Interpreter Docs](https://platform.openai.com/docs/guides/tools-code-interpreter) - Official OpenAI documentation
|
||||
|
|
@ -16,7 +16,7 @@ LiteLLM provides image editing functionality that maps to OpenAI's `/images/edit
|
|||
| Supported operations | Create image edits | Single and multiple images supported |
|
||||
| Supported LiteLLM SDK Versions | 1.63.8+ | Gemini support requires 1.79.3+ |
|
||||
| Supported LiteLLM Proxy Versions | 1.71.1+ | Gemini support requires 1.79.3+ |
|
||||
| Supported LLM providers | **OpenAI**, **Gemini (Google AI Studio)** | Gemini supports the new `gemini-2.5-flash-image` family |
|
||||
| Supported LLM providers | **OpenAI**, **Gemini (Google AI Studio)**, **Vertex AI** | Gemini supports the new `gemini-2.5-flash-image` family. Vertex AI supports both Gemini and Imagen models. |
|
||||
|
||||
#### ⚡️See all supported models and providers at [models.litellm.ai](https://models.litellm.ai/)
|
||||
|
||||
|
|
@ -197,6 +197,53 @@ for idx, image_obj in enumerate(response.data):
|
|||
f.write(base64.b64decode(image_obj.b64_json))
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="vertex_ai" label="Vertex AI">
|
||||
|
||||
#### Basic Image Edit (Gemini)
|
||||
```python showLineNumbers title="Vertex AI Gemini Image Edit"
|
||||
import os
|
||||
import litellm
|
||||
|
||||
# Set Vertex AI credentials
|
||||
os.environ["VERTEXAI_PROJECT"] = "your-gcp-project-id"
|
||||
os.environ["VERTEXAI_LOCATION"] = "us-central1"
|
||||
os.environ["GOOGLE_APPLICATION_CREDENTIALS"] = "/path/to/service-account.json"
|
||||
|
||||
response = litellm.image_edit(
|
||||
model="vertex_ai/gemini-2.5-flash",
|
||||
image=open("original_image.png", "rb"),
|
||||
prompt="Add neon lights in the background",
|
||||
size="1024x1024",
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
#### Image Edit with Imagen (Supports Masks)
|
||||
```python showLineNumbers title="Vertex AI Imagen Image Edit"
|
||||
import os
|
||||
import litellm
|
||||
|
||||
# Set Vertex AI credentials
|
||||
os.environ["VERTEXAI_PROJECT"] = "your-gcp-project-id"
|
||||
os.environ["VERTEXAI_LOCATION"] = "us-central1"
|
||||
os.environ["GOOGLE_APPLICATION_CREDENTIALS"] = "/path/to/service-account.json"
|
||||
|
||||
# Imagen supports mask for inpainting
|
||||
response = litellm.image_edit(
|
||||
model="vertex_ai/imagen-3.0-capability-001",
|
||||
image=open("original_image.png", "rb"),
|
||||
mask=open("mask_image.png", "rb"), # Optional: for inpainting
|
||||
prompt="Turn this into watercolor style scenery",
|
||||
n=2, # Number of variations
|
||||
size="1024x1024",
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
|
@ -302,6 +349,55 @@ curl -X POST "http://0.0.0.0:4000/v1/images/edits" \
|
|||
-F "size=1024x1024"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="vertex_ai" label="Vertex AI">
|
||||
|
||||
1. Add Vertex AI image edit models to your `config.yaml`:
|
||||
```yaml showLineNumbers title="Vertex AI Proxy Configuration"
|
||||
model_list:
|
||||
- model_name: vertex-gemini-image-edit
|
||||
litellm_params:
|
||||
model: vertex_ai/gemini-2.5-flash
|
||||
vertex_project: os.environ/VERTEXAI_PROJECT
|
||||
vertex_location: os.environ/VERTEXAI_LOCATION
|
||||
vertex_credentials: os.environ/GOOGLE_APPLICATION_CREDENTIALS
|
||||
|
||||
- model_name: vertex-imagen-image-edit
|
||||
litellm_params:
|
||||
model: vertex_ai/imagen-3.0-capability-001
|
||||
vertex_project: os.environ/VERTEXAI_PROJECT
|
||||
vertex_location: os.environ/VERTEXAI_LOCATION
|
||||
vertex_credentials: os.environ/GOOGLE_APPLICATION_CREDENTIALS
|
||||
```
|
||||
|
||||
2. Start the LiteLLM proxy server:
|
||||
```bash showLineNumbers title="Start LiteLLM Proxy Server"
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
3. Make an image edit request:
|
||||
```bash showLineNumbers title="Vertex AI Gemini Proxy Image Edit"
|
||||
curl -X POST "http://0.0.0.0:4000/v1/images/edits" \
|
||||
-H "Authorization: Bearer <YOUR-LITELLM-KEY>" \
|
||||
-F "model=vertex-gemini-image-edit" \
|
||||
-F "image=@original_image.png" \
|
||||
-F "prompt=Add neon lights in the background" \
|
||||
-F "size=1024x1024"
|
||||
```
|
||||
|
||||
4. Imagen image edit with mask:
|
||||
```bash showLineNumbers title="Vertex AI Imagen Proxy Image Edit with Mask"
|
||||
curl -X POST "http://0.0.0.0:4000/v1/images/edits" \
|
||||
-H "Authorization: Bearer <YOUR-LITELLM-KEY>" \
|
||||
-F "model=vertex-imagen-image-edit" \
|
||||
-F "image=@original_image.png" \
|
||||
-F "mask=@mask_image.png" \
|
||||
-F "prompt=Turn this into watercolor style scenery" \
|
||||
-F "n=2" \
|
||||
-F "size=1024x1024"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
|
|
|||
|
|
@ -7,42 +7,42 @@ https://github.com/BerriAI/litellm
|
|||
|
||||
## **Call 100+ LLMs using the OpenAI Input/Output Format**
|
||||
|
||||
- Translate inputs to provider's `completion`, `embedding`, and `image_generation` endpoints
|
||||
- [Consistent output](https://docs.litellm.ai/docs/completion/output), text responses will always be available at `['choices'][0]['message']['content']`
|
||||
- Translate inputs to provider's endpoints (`/chat/completions`, `/responses`, `/embeddings`, `/images`, `/audio`, `/batches`, and more)
|
||||
- [Consistent output](https://docs.litellm.ai/docs/supported_endpoints) - same response format regardless of which provider you use
|
||||
- Retry/fallback logic across multiple deployments (e.g. Azure/OpenAI) - [Router](https://docs.litellm.ai/docs/routing)
|
||||
- Track spend & set budgets per project [LiteLLM Proxy Server](https://docs.litellm.ai/docs/simple_proxy)
|
||||
|
||||
## How to use LiteLLM
|
||||
You can use litellm through either:
|
||||
1. [LiteLLM Proxy Server](#litellm-proxy-server-llm-gateway) - Server (LLM Gateway) to call 100+ LLMs, load balance, cost tracking across projects
|
||||
2. [LiteLLM python SDK](#basic-usage) - Python Client to call 100+ LLMs, load balance, cost tracking
|
||||
|
||||
### **When to use LiteLLM Proxy Server (LLM Gateway)**
|
||||
You can use LiteLLM through either the Proxy Server or Python SDK. Both gives you a unified interface to access multiple LLMs (100+ LLMs). Choose the option that best fits your needs:
|
||||
|
||||
:::tip
|
||||
<table style={{width: '100%', tableLayout: 'fixed'}}>
|
||||
<thead>
|
||||
<tr>
|
||||
<th style={{width: '14%'}}></th>
|
||||
<th style={{width: '43%'}}><strong><a href="#litellm-proxy-server-llm-gateway">LiteLLM Proxy Server</a></strong></th>
|
||||
<th style={{width: '43%'}}><strong><a href="#basic-usage">LiteLLM Python SDK</a></strong></th>
|
||||
</tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
<tr>
|
||||
<td style={{width: '14%'}}><strong>Use Case</strong></td>
|
||||
<td style={{width: '43%'}}>Central service (LLM Gateway) to access multiple LLMs</td>
|
||||
<td style={{width: '43%'}}>Use LiteLLM directly in your Python code</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td style={{width: '14%'}}><strong>Who Uses It?</strong></td>
|
||||
<td style={{width: '43%'}}>Gen AI Enablement / ML Platform Teams</td>
|
||||
<td style={{width: '43%'}}>Developers building LLM projects</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td style={{width: '14%'}}><strong>Key Features</strong></td>
|
||||
<td style={{width: '43%'}}>• Centralized API gateway with authentication & authorization<br />• Multi-tenant cost tracking and spend management per project/user<br />• Per-project customization (logging, guardrails, caching)<br />• Virtual keys for secure access control<br />• Admin dashboard UI for monitoring and management</td>
|
||||
<td style={{width: '43%'}}>• Direct Python library integration in your codebase<br />• Router with retry/fallback logic across multiple deployments (e.g. Azure/OpenAI) - <a href="https://docs.litellm.ai/docs/routing">Router</a><br />• Application-level load balancing and cost tracking<br />• Exception handling with OpenAI-compatible errors<br />• Observability callbacks (Lunary, MLflow, Langfuse, etc.)</td>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
|
||||
Use LiteLLM Proxy Server if you want a **central service (LLM Gateway) to access multiple LLMs**
|
||||
|
||||
Typically used by Gen AI Enablement / ML PLatform Teams
|
||||
|
||||
:::
|
||||
|
||||
- LiteLLM Proxy gives you a unified interface to access multiple LLMs (100+ LLMs)
|
||||
- Track LLM Usage and setup guardrails
|
||||
- Customize Logging, Guardrails, Caching per project
|
||||
|
||||
### **When to use LiteLLM Python SDK**
|
||||
|
||||
:::tip
|
||||
|
||||
Use LiteLLM Python SDK if you want to use LiteLLM in your **python code**
|
||||
|
||||
Typically used by developers building llm projects
|
||||
|
||||
:::
|
||||
|
||||
- LiteLLM SDK gives you a unified interface to access multiple LLMs (100+ LLMs)
|
||||
- Retry/fallback logic across multiple deployments (e.g. Azure/OpenAI) - [Router](https://docs.litellm.ai/docs/routing)
|
||||
|
||||
## **LiteLLM Python SDK**
|
||||
|
||||
|
|
@ -245,7 +245,7 @@ response = completion(
|
|||
|
||||
</Tabs>
|
||||
|
||||
### Response Format (OpenAI Format)
|
||||
### Response Format (OpenAI Chat Completions Format)
|
||||
|
||||
```json
|
||||
{
|
||||
|
|
@ -514,15 +514,22 @@ response = completion(
|
|||
LiteLLM maps exceptions across all supported providers to the OpenAI exceptions. All our exceptions inherit from OpenAI's exception types, so any error-handling you have for that, should work out of the box with LiteLLM.
|
||||
|
||||
```python
|
||||
from openai.error import OpenAIError
|
||||
import litellm
|
||||
from litellm import completion
|
||||
import os
|
||||
|
||||
os.environ["ANTHROPIC_API_KEY"] = "bad-key"
|
||||
try:
|
||||
# some code
|
||||
completion(model="claude-instant-1", messages=[{"role": "user", "content": "Hey, how's it going?"}])
|
||||
except OpenAIError as e:
|
||||
print(e)
|
||||
completion(model="anthropic/claude-instant-1", messages=[{"role": "user", "content": "Hey, how's it going?"}])
|
||||
except litellm.AuthenticationError as e:
|
||||
# Thrown when the API key is invalid
|
||||
print(f"Authentication failed: {e}")
|
||||
except litellm.RateLimitError as e:
|
||||
# Thrown when you've exceeded your rate limit
|
||||
print(f"Rate limited: {e}")
|
||||
except litellm.APIError as e:
|
||||
# Thrown for general API errors
|
||||
print(f"API error: {e}")
|
||||
```
|
||||
### See How LiteLLM Transforms Your Requests
|
||||
|
||||
|
|
|
|||
30
docs/my-website/docs/integrations/community.md
Normal file
30
docs/my-website/docs/integrations/community.md
Normal file
|
|
@ -0,0 +1,30 @@
|
|||
# Be an Integration Partner
|
||||
|
||||
Welcome, integration partners! 👋
|
||||
|
||||
We're excited to have you contribute to LiteLLM. To get started and connect with the LiteLLM community:
|
||||
|
||||
## Get Support & Connect
|
||||
|
||||
**Fill out our support form to join the community:**
|
||||
|
||||
👉 [**https://www.litellm.ai/support**](https://www.litellm.ai/support)
|
||||
|
||||
By filling out this form, you'll be able to:
|
||||
- Join our **OSS Slack community** for real-time discussions
|
||||
- Get help and feedback on your integration
|
||||
- Connect with other developers and contributors
|
||||
- Stay updated on the latest LiteLLM developments
|
||||
|
||||
## What We Offer Integration Partners
|
||||
|
||||
- **Direct support** from the LiteLLM team
|
||||
- **Feedback** on your integration implementation
|
||||
- **Collaboration** with a growing community of LLM developers
|
||||
- **Visibility** for your integration in our documentation
|
||||
|
||||
## Questions?
|
||||
|
||||
Once you've joined our Slack community, head over to the **`#integration-partners`** channel to introduce yourself and ask questions. Our team and community members are happy to help you build great integrations with LiteLLM.
|
||||
|
||||
We look forward to working with you! 🚀
|
||||
|
|
@ -211,11 +211,12 @@ mcp_servers:
|
|||
oauth2_example:
|
||||
url: "https://my-mcp-server.com/mcp"
|
||||
auth_type: "oauth2" # 👈 KEY CHANGE
|
||||
authorization_url: "https://my-mcp-server.com/oauth/authorize" # optional for client-credentials
|
||||
token_url: "https://my-mcp-server.com/oauth/token" # required
|
||||
authorization_url: "https://my-mcp-server.com/oauth/authorize" # optional override
|
||||
token_url: "https://my-mcp-server.com/oauth/token" # optional override
|
||||
registration_url: "https://my-mcp-server.com/oauth/register" # optional override
|
||||
client_id: os.environ/OAUTH_CLIENT_ID
|
||||
client_secret: os.environ/OAUTH_CLIENT_SECRET
|
||||
scopes: ["tool.read", "tool.write"] # optional
|
||||
scopes: ["tool.read", "tool.write"] # optional override
|
||||
|
||||
bearer_example:
|
||||
url: "https://my-mcp-server.com/mcp"
|
||||
|
|
@ -247,6 +248,41 @@ mcp_servers:
|
|||
X-Custom-Header: "some-value"
|
||||
```
|
||||
|
||||
### MCP Walkthroughs
|
||||
|
||||
- **Strands (STDIO)** – [watch tutorial](https://screen.studio/share/ruv4D73F)
|
||||
|
||||
> Add it from the UI
|
||||
|
||||
```json title="strands-mcp" showLineNumbers
|
||||
{
|
||||
"mcpServers": {
|
||||
"strands-agents": {
|
||||
"command": "uvx",
|
||||
"args": ["strands-agents-mcp-server"],
|
||||
"env": {
|
||||
"FASTMCP_LOG_LEVEL": "INFO"
|
||||
},
|
||||
"disabled": false,
|
||||
"autoApprove": ["search_docs", "fetch_doc"]
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
> config.yml
|
||||
|
||||
```yaml title="config.yml – strands MCP" showLineNumbers
|
||||
mcp_servers:
|
||||
strands_mcp:
|
||||
transport: "stdio"
|
||||
command: "uvx"
|
||||
args: ["strands-agents-mcp-server"]
|
||||
env:
|
||||
FASTMCP_LOG_LEVEL: "INFO"
|
||||
```
|
||||
|
||||
|
||||
### MCP Aliases
|
||||
|
||||
You can define aliases for your MCP servers in the `litellm_settings` section. This allows you to:
|
||||
|
|
@ -277,14 +313,14 @@ litellm_settings:
|
|||
|
||||
LiteLLM can automatically convert OpenAPI specifications into MCP servers, allowing you to expose any REST API as MCP tools. This is useful when you have existing APIs with OpenAPI/Swagger documentation and want to make them available as MCP tools.
|
||||
|
||||
### Benefits
|
||||
**Benefits:**
|
||||
|
||||
- **Rapid Integration**: Convert existing APIs to MCP tools without writing custom MCP server code
|
||||
- **Automatic Tool Generation**: LiteLLM automatically generates MCP tools from your OpenAPI spec
|
||||
- **Unified Interface**: Use the same MCP interface for both native MCP servers and OpenAPI-based APIs
|
||||
- **Easy Testing**: Test and iterate on API integrations quickly
|
||||
|
||||
### Configuration
|
||||
**Configuration:**
|
||||
|
||||
Add your OpenAPI-based MCP server to your `config.yaml`:
|
||||
|
||||
|
|
@ -317,7 +353,7 @@ mcp_servers:
|
|||
auth_value: "your-bearer-token"
|
||||
```
|
||||
|
||||
### Configuration Parameters
|
||||
**Configuration Parameters:**
|
||||
|
||||
| Parameter | Required | Description |
|
||||
|-----------|----------|-------------|
|
||||
|
|
@ -325,6 +361,10 @@ mcp_servers:
|
|||
| `spec_path` | Yes | Path or URL to your OpenAPI specification file (JSON or YAML) |
|
||||
| `auth_type` | No | Authentication type: `none`, `api_key`, `bearer_token`, `basic`, `authorization` |
|
||||
| `auth_value` | No | Authentication value (required if `auth_type` is set) |
|
||||
| `authorization_url` | No | For `auth_type: oauth2`. Optional override; if omitted LiteLLM auto-discovers it. |
|
||||
| `token_url` | No | For `auth_type: oauth2`. Optional override; if omitted LiteLLM auto-discovers it. |
|
||||
| `registration_url` | No | For `auth_type: oauth2`. Optional override; if omitted LiteLLM auto-discovers it. |
|
||||
| `scopes` | No | For `auth_type: oauth2`. Optional override; if omitted LiteLLM uses the scopes advertised by the server. |
|
||||
| `description` | No | Optional description for the MCP server |
|
||||
| `allowed_tools` | No | List of specific tools to allow (see [MCP Tool Filtering](#mcp-tool-filtering)) |
|
||||
| `disallowed_tools` | No | List of specific tools to block (see [MCP Tool Filtering](#mcp-tool-filtering)) |
|
||||
|
|
@ -425,7 +465,7 @@ curl --location 'https://api.openai.com/v1/responses' \
|
|||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### How It Works
|
||||
**How It Works**
|
||||
|
||||
1. **Spec Loading**: LiteLLM loads your OpenAPI specification from the provided `spec_path`
|
||||
2. **Tool Generation**: Each API endpoint in the spec becomes an MCP tool
|
||||
|
|
@ -433,7 +473,7 @@ curl --location 'https://api.openai.com/v1/responses' \
|
|||
4. **Request Handling**: When a tool is called, LiteLLM converts the MCP request to the appropriate HTTP request
|
||||
5. **Response Translation**: API responses are converted back to MCP format
|
||||
|
||||
### OpenAPI Spec Requirements
|
||||
**OpenAPI Spec Requirements**
|
||||
|
||||
Your OpenAPI specification should follow standard OpenAPI/Swagger conventions:
|
||||
- **Supported versions**: OpenAPI 3.0.x, OpenAPI 3.1.x, Swagger 2.0
|
||||
|
|
@ -441,585 +481,94 @@ Your OpenAPI specification should follow standard OpenAPI/Swagger conventions:
|
|||
- **Operation IDs**: Each operation should have a unique `operationId` (this becomes the tool name)
|
||||
- **Parameters**: Request parameters should be properly documented with types and descriptions
|
||||
|
||||
### Example OpenAPI Spec Structure
|
||||
## MCP Oauth
|
||||
|
||||
```yaml title="sample-openapi.yaml" showLineNumbers
|
||||
openapi: 3.0.0
|
||||
info:
|
||||
title: My API
|
||||
version: 1.0.0
|
||||
paths:
|
||||
/pets/{petId}:
|
||||
get:
|
||||
operationId: getPetById
|
||||
summary: Get a pet by ID
|
||||
parameters:
|
||||
- name: petId
|
||||
in: path
|
||||
required: true
|
||||
schema:
|
||||
type: integer
|
||||
responses:
|
||||
'200':
|
||||
description: Successful response
|
||||
content:
|
||||
application/json:
|
||||
schema:
|
||||
type: object
|
||||
```
|
||||
LiteLLM v 1.77.6 added support for OAuth 2.0 Client Credentials for MCP servers.
|
||||
|
||||
## Allow/Disallow MCP Tools
|
||||
|
||||
Control which tools are available from your MCP servers. You can either allow only specific tools or block dangerous ones.
|
||||
This configuration is currently available on the config.yaml, with UI support coming soon.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="allowed" label="Only Allow Specific Tools">
|
||||
|
||||
Use `allowed_tools` to specify exactly which tools users can access. All other tools will be blocked.
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
```yaml
|
||||
mcp_servers:
|
||||
github_mcp:
|
||||
url: "https://api.githubcopilot.com/mcp"
|
||||
auth_type: oauth2
|
||||
authorization_url: https://github.com/login/oauth/authorize
|
||||
token_url: https://github.com/login/oauth/access_token
|
||||
client_id: os.environ/GITHUB_OAUTH_CLIENT_ID
|
||||
client_secret: os.environ/GITHUB_OAUTH_CLIENT_SECRET
|
||||
scopes: ["public_repo", "user:email"]
|
||||
allowed_tools: ["list_tools"]
|
||||
# only list_tools will be available
|
||||
```
|
||||
|
||||
**Use this when:**
|
||||
- You want strict control over which tools are available
|
||||
- You're in a high-security environment
|
||||
- You're testing a new MCP server with limited tools
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="blocked" label="Block Specific Tools">
|
||||
|
||||
Use `disallowed_tools` to block specific tools. All other tools will be available.
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
mcp_servers:
|
||||
github_mcp:
|
||||
url: "https://api.githubcopilot.com/mcp"
|
||||
auth_type: oauth2
|
||||
authorization_url: https://github.com/login/oauth/authorize
|
||||
token_url: https://github.com/login/oauth/access_token
|
||||
client_id: os.environ/GITHUB_OAUTH_CLIENT_ID
|
||||
client_secret: os.environ/GITHUB_OAUTH_CLIENT_SECRET
|
||||
scopes: ["public_repo", "user:email"]
|
||||
disallowed_tools: ["repo_delete"]
|
||||
# only repo_delete will be blocked
|
||||
```
|
||||
|
||||
**Use this when:**
|
||||
- Most tools are safe, but you want to block a few dangerous ones
|
||||
- You want to prevent expensive API calls
|
||||
- You're gradually adding restrictions to an existing server
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Important Notes
|
||||
|
||||
- If you specify both `allowed_tools` and `disallowed_tools`, the allowed list takes priority
|
||||
- Tool names are case-sensitive
|
||||
|
||||
---
|
||||
|
||||
## Allow/Disallow MCP Tool Parameters
|
||||
|
||||
Control which parameters are allowed for specific MCP tools using the `allowed_params` configuration. This provides fine-grained control over tool usage by restricting the parameters that can be passed to each tool.
|
||||
|
||||
### Configuration
|
||||
|
||||
`allowed_params` is a dictionary that maps tool names to lists of allowed parameter names. When configured, only the specified parameters will be accepted for that tool - any other parameters will be rejected with a 403 error.
|
||||
|
||||
```yaml title="config.yaml with allowed_params" showLineNumbers
|
||||
mcp_servers:
|
||||
deepwiki_mcp:
|
||||
url: https://mcp.deepwiki.com/mcp
|
||||
transport: "http"
|
||||
auth_type: "none"
|
||||
allowed_params:
|
||||
# Tool name: list of allowed parameters
|
||||
read_wiki_contents: ["status"]
|
||||
|
||||
my_api_mcp:
|
||||
url: "https://my-api-server.com"
|
||||
auth_type: "api_key"
|
||||
auth_value: "my-key"
|
||||
allowed_params:
|
||||
# Using unprefixed tool name
|
||||
getpetbyid: ["status"]
|
||||
# Using prefixed tool name (both formats work)
|
||||
my_api_mcp-findpetsbystatus: ["status", "limit"]
|
||||
# Another tool with multiple allowed params
|
||||
create_issue: ["title", "body", "labels"]
|
||||
```
|
||||
[**See Claude Code Tutorial**](./tutorials/claude_responses_api#connecting-mcp-servers)
|
||||
|
||||
### How It Works
|
||||
|
||||
1. **Tool-specific filtering**: Each tool can have its own list of allowed parameters
|
||||
2. **Flexible naming**: Tool names can be specified with or without the server prefix (e.g., both `"getpetbyid"` and `"my_api_mcp-getpetbyid"` work)
|
||||
3. **Whitelist approach**: Only parameters in the allowed list are permitted
|
||||
4. **Unlisted tools**: If `allowed_params` is not set, all parameters are allowed
|
||||
5. **Error handling**: Requests with disallowed parameters receive a 403 error with details about which parameters are allowed
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant Browser as User-Agent (Browser)
|
||||
participant Client as Client
|
||||
participant LiteLLM as LiteLLM Proxy
|
||||
participant MCP as MCP Server (Resource Server)
|
||||
participant Auth as Authorization Server
|
||||
|
||||
### Example Request Behavior
|
||||
Note over Client,LiteLLM: Step 1 – Resource discovery
|
||||
Client->>LiteLLM: GET /.well-known/oauth-protected-resource/{mcp_server_name}/mcp
|
||||
LiteLLM->>Client: Return resource metadata
|
||||
|
||||
With the configuration above, here's how requests would be handled:
|
||||
Note over Client,LiteLLM: Step 2 – Authorization server discovery
|
||||
Client->>LiteLLM: GET /.well-known/oauth-authorization-server/{mcp_server_name}
|
||||
LiteLLM->>Client: Return authorization server metadata
|
||||
|
||||
**✅ Allowed Request:**
|
||||
```json
|
||||
{
|
||||
"tool": "read_wiki_contents",
|
||||
"arguments": {
|
||||
"status": "active"
|
||||
}
|
||||
}
|
||||
Note over Client,Auth: Step 3 – Dynamic client registration
|
||||
Client->>LiteLLM: POST /{mcp_server_name}/register
|
||||
LiteLLM->>Auth: Forward registration request
|
||||
Auth->>LiteLLM: Issue client credentials
|
||||
LiteLLM->>Client: Return client credentials
|
||||
|
||||
Note over Client,Browser: Step 4 – User authorization (PKCE)
|
||||
Client->>Browser: Open authorization URL + code_challenge + resource
|
||||
Browser->>Auth: Authorization request
|
||||
Note over Auth: User authorizes
|
||||
Auth->>Browser: Redirect with authorization code
|
||||
Browser->>LiteLLM: Callback to LiteLLM with code
|
||||
LiteLLM->>Browser: Redirect back with authorization code
|
||||
Browser->>Client: Callback with authorization code
|
||||
|
||||
Note over Client,Auth: Step 5 – Token exchange
|
||||
Client->>LiteLLM: Token request + code_verifier + resource
|
||||
LiteLLM->>Auth: Forward token request
|
||||
Auth->>LiteLLM: Access (and refresh) token
|
||||
LiteLLM->>Client: Return tokens
|
||||
|
||||
Note over Client,MCP: Step 6 – Authenticated MCP call
|
||||
Client->>LiteLLM: MCP request with access token + LiteLLM API key
|
||||
LiteLLM->>MCP: MCP request with Bearer token
|
||||
MCP-->>LiteLLM: MCP response
|
||||
LiteLLM-->>Client: Return MCP response
|
||||
```
|
||||
|
||||
**❌ Rejected Request:**
|
||||
```json
|
||||
{
|
||||
"tool": "read_wiki_contents",
|
||||
"arguments": {
|
||||
"status": "active",
|
||||
"limit": 10 // This parameter is not allowed
|
||||
}
|
||||
}
|
||||
```
|
||||
**Participants**
|
||||
|
||||
**Error Response:**
|
||||
```json
|
||||
{
|
||||
"error": "Parameters ['limit'] are not allowed for tool read_wiki_contents. Allowed parameters: ['status']. Contact proxy admin to allow these parameters."
|
||||
}
|
||||
```
|
||||
- **Client** – The MCP-capable AI agent (e.g., Claude Code, Cursor, or another IDE/agent) that initiates OAuth discovery, authorization, and tool invocations on behalf of the user.
|
||||
- **LiteLLM Proxy** – Mediates all OAuth discovery, registration, token exchange, and MCP traffic while protecting stored credentials.
|
||||
- **Authorization Server** – Issues OAuth 2.0 tokens via dynamic client registration, PKCE authorization, and token endpoints.
|
||||
- **MCP Server (Resource Server)** – The protected MCP endpoint that receives LiteLLM’s authenticated JSON-RPC requests.
|
||||
- **User-Agent (Browser)** – Temporarily involved so the end user can grant consent during the authorization step.
|
||||
|
||||
### Use Cases
|
||||
**Flow Steps**
|
||||
|
||||
- **Security**: Prevent users from accessing sensitive parameters or dangerous operations
|
||||
- **Cost control**: Restrict expensive parameters (e.g., limiting result counts)
|
||||
- **Compliance**: Enforce parameter usage policies for regulatory requirements
|
||||
- **Staged rollouts**: Gradually enable parameters as tools are tested
|
||||
- **Multi-tenant isolation**: Different parameter access for different user groups
|
||||
1. **Resource Discovery**: The client fetches MCP resource metadata from LiteLLM’s `.well-known/oauth-protected-resource` endpoint to understand scopes and capabilities.
|
||||
2. **Authorization Server Discovery**: The client retrieves the OAuth server metadata (token endpoint, authorization endpoint, supported PKCE methods) through LiteLLM’s `.well-known/oauth-authorization-server` endpoint.
|
||||
3. **Dynamic Client Registration**: The client registers through LiteLLM, which forwards the request to the authorization server (RFC 7591). If the provider doesn’t support dynamic registration, you can pre-store `client_id`/`client_secret` in LiteLLM (e.g., GitHub MCP) and the flow proceeds the same way.
|
||||
4. **User Authorization**: The client launches a browser session (with code challenge and resource hints). The user approves access, the authorization server sends the code through LiteLLM back to the client.
|
||||
5. **Token Exchange**: The client calls LiteLLM with the authorization code, code verifier, and resource. LiteLLM exchanges them with the authorization server and returns the issued access/refresh tokens.
|
||||
6. **MCP Invocation**: With a valid token, the client sends the MCP JSON-RPC request (plus LiteLLM API key) to LiteLLM, which forwards it to the MCP server and relays the tool response.
|
||||
|
||||
### Combining with Tool Filtering
|
||||
|
||||
`allowed_params` works alongside `allowed_tools` and `disallowed_tools` for complete control:
|
||||
|
||||
```yaml title="Combined filtering example" showLineNumbers
|
||||
mcp_servers:
|
||||
github_mcp:
|
||||
url: "https://api.githubcopilot.com/mcp"
|
||||
auth_type: oauth2
|
||||
authorization_url: https://github.com/login/oauth/authorize
|
||||
token_url: https://github.com/login/oauth/access_token
|
||||
client_id: os.environ/GITHUB_OAUTH_CLIENT_ID
|
||||
client_secret: os.environ/GITHUB_OAUTH_CLIENT_SECRET
|
||||
scopes: ["public_repo", "user:email"]
|
||||
# Only allow specific tools
|
||||
allowed_tools: ["create_issue", "list_issues", "search_issues"]
|
||||
# Block dangerous operations
|
||||
disallowed_tools: ["delete_repo"]
|
||||
# Restrict parameters per tool
|
||||
allowed_params:
|
||||
create_issue: ["title", "body", "labels"]
|
||||
list_issues: ["state", "sort", "perPage"]
|
||||
search_issues: ["query", "sort", "order", "perPage"]
|
||||
```
|
||||
|
||||
This configuration ensures that:
|
||||
1. Only the three listed tools are available
|
||||
2. The `delete_repo` tool is explicitly blocked
|
||||
3. Each tool can only use its specified parameters
|
||||
|
||||
---
|
||||
|
||||
## MCP Server Access Control
|
||||
|
||||
LiteLLM Proxy provides two methods for controlling access to specific MCP servers:
|
||||
|
||||
1. **URL-based Namespacing** - Use URL paths to directly access specific servers or access groups
|
||||
2. **Header-based Namespacing** - Use the `x-mcp-servers` header to specify which servers to access
|
||||
|
||||
---
|
||||
|
||||
### Method 1: URL-based Namespacing
|
||||
|
||||
LiteLLM Proxy supports URL-based namespacing for MCP servers using the format `/mcp/<servers or access groups>`. This allows you to:
|
||||
|
||||
- **Direct URL Access**: Point MCP clients directly to specific servers or access groups via URL
|
||||
- **Simplified Configuration**: Use URLs instead of headers for server selection
|
||||
- **Access Group Support**: Use access group names in URLs for grouped server access
|
||||
|
||||
#### URL Format
|
||||
|
||||
```
|
||||
<your-litellm-proxy-base-url>/mcp/<server_alias_or_access_group>
|
||||
```
|
||||
|
||||
**Examples:**
|
||||
- `/mcp/github` - Access tools from the "github" MCP server
|
||||
- `/mcp/zapier` - Access tools from the "zapier" MCP server
|
||||
- `/mcp/dev_group` - Access tools from all servers in the "dev_group" access group
|
||||
- `/mcp/github,zapier` - Access tools from multiple specific servers
|
||||
|
||||
#### Usage Examples
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="openai" label="OpenAI API">
|
||||
|
||||
```bash title="cURL Example with URL Namespacing" showLineNumbers
|
||||
curl --location 'https://api.openai.com/v1/responses' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header "Authorization: Bearer $OPENAI_API_KEY" \
|
||||
--data '{
|
||||
"model": "gpt-4o",
|
||||
"tools": [
|
||||
{
|
||||
"type": "mcp",
|
||||
"server_label": "litellm",
|
||||
"server_url": "<your-litellm-proxy-base-url>/mcp/github",
|
||||
"require_approval": "never",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer YOUR_LITELLM_API_KEY"
|
||||
}
|
||||
}
|
||||
],
|
||||
"input": "Run available tools",
|
||||
"tool_choice": "required"
|
||||
}'
|
||||
```
|
||||
|
||||
This example uses URL namespacing to access only the "github" MCP server.
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="litellm" label="LiteLLM Proxy">
|
||||
|
||||
```bash title="cURL Example with URL Namespacing" showLineNumbers
|
||||
curl --location '<your-litellm-proxy-base-url>/v1/responses' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header "Authorization: Bearer $LITELLM_API_KEY" \
|
||||
--data '{
|
||||
"model": "gpt-4o",
|
||||
"tools": [
|
||||
{
|
||||
"type": "mcp",
|
||||
"server_label": "litellm",
|
||||
"server_url": "<your-litellm-proxy-base-url>/mcp/dev_group",
|
||||
"require_approval": "never",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer YOUR_LITELLM_API_KEY"
|
||||
}
|
||||
}
|
||||
],
|
||||
"input": "Run available tools",
|
||||
"tool_choice": "required"
|
||||
}'
|
||||
```
|
||||
|
||||
This example uses URL namespacing to access all servers in the "dev_group" access group.
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="cursor" label="Cursor IDE">
|
||||
|
||||
```json title="Cursor MCP Configuration with URL Namespacing" showLineNumbers
|
||||
{
|
||||
"mcpServers": {
|
||||
"LiteLLM": {
|
||||
"url": "<your-litellm-proxy-base-url>/mcp/github,zapier",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer $LITELLM_API_KEY"
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
This configuration uses URL namespacing to access tools from both "github" and "zapier" MCP servers.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
#### Benefits of URL Namespacing
|
||||
|
||||
- **Direct Access**: No need for additional headers to specify servers
|
||||
- **Clean URLs**: Self-documenting URLs that clearly indicate which servers are accessible
|
||||
- **Access Group Support**: Use access group names for grouped server access
|
||||
- **Multiple Servers**: Specify multiple servers in a single URL with comma separation
|
||||
- **Simplified Configuration**: Easier setup for MCP clients that prefer URL-based configuration
|
||||
|
||||
---
|
||||
|
||||
### Method 2: Header-based Namespacing
|
||||
|
||||
You can choose to access specific MCP servers and only list their tools using the `x-mcp-servers` header. This header allows you to:
|
||||
- Limit tool access to one or more specific MCP servers
|
||||
- Control which tools are available in different environments or use cases
|
||||
|
||||
The header accepts a comma-separated list of server aliases: `"alias_1,Server2,Server3"`
|
||||
|
||||
**Notes:**
|
||||
- If the header is not provided, tools from all available MCP servers will be accessible
|
||||
- This method works with the standard LiteLLM MCP endpoint
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="openai" label="OpenAI API">
|
||||
|
||||
```bash title="cURL Example with Header Namespacing" showLineNumbers
|
||||
curl --location 'https://api.openai.com/v1/responses' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header "Authorization: Bearer $OPENAI_API_KEY" \
|
||||
--data '{
|
||||
"model": "gpt-4o",
|
||||
"tools": [
|
||||
{
|
||||
"type": "mcp",
|
||||
"server_label": "litellm",
|
||||
"server_url": "<your-litellm-proxy-base-url>/mcp/",
|
||||
"require_approval": "never",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer YOUR_LITELLM_API_KEY",
|
||||
"x-mcp-servers": "alias_1"
|
||||
}
|
||||
}
|
||||
],
|
||||
"input": "Run available tools",
|
||||
"tool_choice": "required"
|
||||
}'
|
||||
```
|
||||
|
||||
In this example, the request will only have access to tools from the "alias_1" MCP server.
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="litellm" label="LiteLLM Proxy">
|
||||
|
||||
```bash title="cURL Example with Header Namespacing" showLineNumbers
|
||||
curl --location '<your-litellm-proxy-base-url>/v1/responses' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header "Authorization: Bearer $LITELLM_API_KEY" \
|
||||
--data '{
|
||||
"model": "gpt-4o",
|
||||
"tools": [
|
||||
{
|
||||
"type": "mcp",
|
||||
"server_label": "litellm",
|
||||
"server_url": "<your-litellm-proxy-base-url>/mcp/",
|
||||
"require_approval": "never",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer YOUR_LITELLM_API_KEY",
|
||||
"x-mcp-servers": "alias_1,Server2"
|
||||
}
|
||||
}
|
||||
],
|
||||
"input": "Run available tools",
|
||||
"tool_choice": "required"
|
||||
}'
|
||||
```
|
||||
|
||||
This configuration restricts the request to only use tools from the specified MCP servers.
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="cursor" label="Cursor IDE">
|
||||
|
||||
```json title="Cursor MCP Configuration with Header Namespacing" showLineNumbers
|
||||
{
|
||||
"mcpServers": {
|
||||
"LiteLLM": {
|
||||
"url": "<your-litellm-proxy-base-url>/mcp/",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer $LITELLM_API_KEY",
|
||||
"x-mcp-servers": "alias_1,Server2"
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
This configuration in Cursor IDE settings will limit tool access to only the specified MCP servers.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
---
|
||||
|
||||
### Comparison: Header vs URL Namespacing
|
||||
|
||||
| Feature | Header Namespacing | URL Namespacing |
|
||||
|---------|-------------------|-----------------|
|
||||
| **Method** | Uses `x-mcp-servers` header | Uses URL path `/mcp/<servers>` |
|
||||
| **Endpoint** | Standard `litellm_proxy` endpoint | Custom `/mcp/<servers>` endpoint |
|
||||
| **Configuration** | Requires additional header | Self-contained in URL |
|
||||
| **Multiple Servers** | Comma-separated in header | Comma-separated in URL path |
|
||||
| **Access Groups** | Supported via header | Supported via URL path |
|
||||
| **Client Support** | Works with all MCP clients | Works with URL-aware MCP clients |
|
||||
| **Use Case** | Dynamic server selection | Fixed server configuration |
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="openai" label="OpenAI API">
|
||||
|
||||
```bash title="cURL Example with Server Segregation" showLineNumbers
|
||||
curl --location 'https://api.openai.com/v1/responses' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header "Authorization: Bearer $OPENAI_API_KEY" \
|
||||
--data '{
|
||||
"model": "gpt-4o",
|
||||
"tools": [
|
||||
{
|
||||
"type": "mcp",
|
||||
"server_label": "litellm",
|
||||
"server_url": "<your-litellm-proxy-base-url>/mcp/",
|
||||
"require_approval": "never",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer YOUR_LITELLM_API_KEY",
|
||||
"x-mcp-servers": "alias_1"
|
||||
}
|
||||
}
|
||||
],
|
||||
"input": "Run available tools",
|
||||
"tool_choice": "required"
|
||||
}'
|
||||
```
|
||||
|
||||
In this example, the request will only have access to tools from the "alias_1" MCP server.
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="litellm" label="LiteLLM Proxy">
|
||||
|
||||
```bash title="cURL Example with Server Segregation" showLineNumbers
|
||||
curl --location '<your-litellm-proxy-base-url>/v1/responses' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header "Authorization: Bearer $LITELLM_API_KEY" \
|
||||
--data '{
|
||||
"model": "gpt-4o",
|
||||
"tools": [
|
||||
{
|
||||
"type": "mcp",
|
||||
"server_label": "litellm",
|
||||
"server_url": "litellm_proxy",
|
||||
"require_approval": "never",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer YOUR_LITELLM_API_KEY",
|
||||
"x-mcp-servers": "alias_1,Server2"
|
||||
}
|
||||
}
|
||||
],
|
||||
"input": "Run available tools",
|
||||
"tool_choice": "required"
|
||||
}'
|
||||
```
|
||||
|
||||
This configuration restricts the request to only use tools from the specified MCP servers.
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="cursor" label="Cursor IDE">
|
||||
|
||||
```json title="Cursor MCP Configuration with Server Segregation" showLineNumbers
|
||||
{
|
||||
"mcpServers": {
|
||||
"LiteLLM": {
|
||||
"url": "litellm_proxy",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer $LITELLM_API_KEY",
|
||||
"x-mcp-servers": "alias_1,Server2"
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
This configuration in Cursor IDE settings will limit tool access to only the specified MCP server.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Grouping MCPs (Access Groups)
|
||||
|
||||
MCP Access Groups allow you to group multiple MCP servers together for easier management.
|
||||
|
||||
#### 1. Create an Access Group
|
||||
|
||||
##### A. Creating Access Groups using Config:
|
||||
|
||||
```yaml title="Creating access groups for MCP using the config" showLineNumbers
|
||||
mcp_servers:
|
||||
"deepwiki_mcp":
|
||||
url: https://mcp.deepwiki.com/mcp
|
||||
transport: "http"
|
||||
auth_type: "none"
|
||||
access_groups: ["dev_group"]
|
||||
```
|
||||
|
||||
While adding `mcp_servers` using the config:
|
||||
- Pass in a list of strings inside `access_groups`
|
||||
- These groups can then be used for segregating access using keys, teams and MCP clients using headers
|
||||
|
||||
##### B. Creating Access Groups using UI
|
||||
|
||||
To create an access group:
|
||||
- Go to MCP Servers in the LiteLLM UI
|
||||
- Click "Add a New MCP Server"
|
||||
- Under "MCP Access Groups", create a new group (e.g., "dev_group") by typing it
|
||||
- Add the same group name to other servers to group them together
|
||||
|
||||
<Image
|
||||
img={require('../img/mcp_create_access_group.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0'}}
|
||||
/>
|
||||
|
||||
#### 2. Use Access Group in Cursor
|
||||
|
||||
Include the access group name in the `x-mcp-servers` header:
|
||||
|
||||
```json title="Cursor Configuration with Access Groups" showLineNumbers
|
||||
{
|
||||
"mcpServers": {
|
||||
"LiteLLM": {
|
||||
"url": "litellm_proxy",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer $LITELLM_API_KEY",
|
||||
"x-mcp-servers": "dev_group"
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
This gives you access to all servers in the "dev_group" access group.
|
||||
- Which means that if deepwiki server (and any other servers) which have the access group `dev_group` assigned to them will be available for tool calling
|
||||
|
||||
#### Advanced: Connecting Access Groups to API Keys
|
||||
|
||||
When creating API keys, you can assign them to specific access groups for permission management:
|
||||
|
||||
- Go to "Keys" in the LiteLLM UI and click "Create Key"
|
||||
- Select the desired MCP access groups from the dropdown
|
||||
- The key will have access to all MCP servers in those groups
|
||||
- This is reflected in the Test Key page
|
||||
|
||||
<Image
|
||||
img={require('../img/mcp_key_access_group.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0'}}
|
||||
/>
|
||||
See the official [MCP Authorization Flow](https://modelcontextprotocol.io/specification/2025-06-18/basic/authorization#authorization-flow-steps) for additional reference.
|
||||
|
||||
|
||||
## Forwarding Custom Headers to MCP Servers
|
||||
|
||||
LiteLLM supports forwarding additional custom headers from MCP clients to backend MCP servers using the `extra_headers` configuration parameter. This allows you to pass custom authentication tokens, API keys, or other headers that your MCP server requires.
|
||||
|
||||
### Configuration
|
||||
**Configuration**
|
||||
|
||||
|
||||
<Tabs>
|
||||
|
|
@ -1105,7 +654,7 @@ if __name__ == "__main__":
|
|||
</Tabs>
|
||||
|
||||
|
||||
### Client Usage
|
||||
#### Client Usage
|
||||
|
||||
When connecting from MCP clients, include the custom headers that match the `extra_headers` configuration:
|
||||
|
||||
|
|
@ -1190,52 +739,15 @@ curl --location 'http://localhost:4000/github_mcp/mcp' \
|
|||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### How It Works
|
||||
#### How It Works
|
||||
|
||||
1. **Configuration**: Define `extra_headers` in your MCP server config with the header names you want to forward
|
||||
2. **Client Headers**: Include the corresponding headers in your MCP client requests
|
||||
3. **Header Forwarding**: LiteLLM automatically forwards matching headers to the backend MCP server
|
||||
4. **Authentication**: The backend MCP server receives both the configured auth headers and the custom headers
|
||||
|
||||
### Use Cases
|
||||
|
||||
- **Custom Authentication**: Forward custom API keys or tokens required by specific MCP servers
|
||||
- **Request Context**: Pass user identification, session data, or request tracking headers
|
||||
- **Third-party Integration**: Include headers required by external services that your MCP server integrates with
|
||||
- **Multi-tenant Systems**: Forward tenant-specific headers for proper request routing
|
||||
|
||||
### Security Considerations
|
||||
|
||||
- Only headers listed in `extra_headers` are forwarded to maintain security
|
||||
- Sensitive headers should be passed through environment variables when possible
|
||||
- Consider using server-specific auth headers for better security isolation
|
||||
|
||||
---
|
||||
|
||||
## MCP Oauth
|
||||
|
||||
LiteLLM v 1.77.6 added support for OAuth 2.0 Client Credentials for MCP servers.
|
||||
|
||||
|
||||
This configuration is currently available on the config.yaml, with UI support coming soon.
|
||||
|
||||
```yaml
|
||||
mcp_servers:
|
||||
github_mcp:
|
||||
url: "https://api.githubcopilot.com/mcp"
|
||||
auth_type: oauth2
|
||||
authorization_url: https://github.com/login/oauth/authorize
|
||||
token_url: https://github.com/login/oauth/access_token
|
||||
client_id: os.environ/GITHUB_OAUTH_CLIENT_ID
|
||||
client_secret: os.environ/GITHUB_OAUTH_CLIENT_SECRET
|
||||
scopes: ["public_repo", "user:email"]
|
||||
```
|
||||
|
||||
**Note**
|
||||
In the future, users will only need to specify the `url` of the MCP server.
|
||||
LiteLLM will automatically resolve the corresponding `authorization_url`, `token_url`, and `registration_url` based on the MCP server metadata (e.g., `.well-known/oauth-authorization-server` or `oauth-protected-resource`).
|
||||
|
||||
[**See Claude Code Tutorial**](./tutorials/claude_responses_api#connecting-mcp-servers)
|
||||
|
||||
## Using your MCP with client side credentials
|
||||
|
||||
|
|
@ -1625,6 +1137,37 @@ curl --location '<your-litellm-proxy-base-url>/v1/responses' \
|
|||
}'
|
||||
```
|
||||
|
||||
## Use MCP tools with `/chat/completions`
|
||||
|
||||
:::tip Works with all providers
|
||||
This flow is **provider-agnostic**: the same MCP tool definition works for _every_ LLM backend behind LiteLLM (OpenAI, Azure OpenAI, Anthropic, Amazon Bedrock, Vertex, self-hosted deployments, etc.).
|
||||
:::
|
||||
|
||||
LiteLLM Proxy also supports MCP-aware tooling on the classic `/v1/chat/completions` endpoint. Provide the MCP tool definition directly in the `tools` array and LiteLLM will fetch and transform the MCP server's tools into OpenAI-compatible function calls. When `require_approval` is set to `"never"`, the proxy automatically executes the returned tool calls and feeds the results back into the model before returning the assistant response.
|
||||
|
||||
```bash title="Chat Completions with MCP Tools" showLineNumbers
|
||||
curl --location '<your-litellm-proxy-base-url>/v1/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header "Authorization: Bearer $LITELLM_API_KEY" \
|
||||
--data '{
|
||||
"model": "gpt-4o-mini",
|
||||
"messages": [
|
||||
{"role": "user", "content": "Summarize the latest open PR."}
|
||||
],
|
||||
"tools": [
|
||||
{
|
||||
"type": "mcp",
|
||||
"server_url": "litellm_proxy/mcp/github",
|
||||
"server_label": "github_mcp",
|
||||
"require_approval": "never"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
If you omit `require_approval` or set it to any value other than `"never"`, the MCP tool calls are returned to the client so that you can review and execute them manually, matching the upstream OpenAI behavior.
|
||||
|
||||
|
||||
## LiteLLM Proxy - Walk through MCP Gateway
|
||||
LiteLLM exposes an MCP Gateway for admins to add all their MCP servers to LiteLLM. The key benefits of using LiteLLM Proxy with MCP are:
|
||||
|
||||
|
|
@ -1887,4 +1430,4 @@ async with stdio_client(server_params) as (read, write):
|
|||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
</Tabs>
|
||||
|
|
|
|||
|
|
@ -35,6 +35,554 @@ When Creating a Key, Team, or Organization, you can select the allowed MCP Serve
|
|||
/>
|
||||
|
||||
|
||||
## Allow/Disallow MCP Tools
|
||||
|
||||
Control which tools are available from your MCP servers. You can either allow only specific tools or block dangerous ones.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="allowed" label="Only Allow Specific Tools">
|
||||
|
||||
Use `allowed_tools` to specify exactly which tools users can access. All other tools will be blocked.
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
mcp_servers:
|
||||
github_mcp:
|
||||
url: "https://api.githubcopilot.com/mcp"
|
||||
auth_type: oauth2
|
||||
authorization_url: https://github.com/login/oauth/authorize
|
||||
token_url: https://github.com/login/oauth/access_token
|
||||
client_id: os.environ/GITHUB_OAUTH_CLIENT_ID
|
||||
client_secret: os.environ/GITHUB_OAUTH_CLIENT_SECRET
|
||||
scopes: ["public_repo", "user:email"]
|
||||
allowed_tools: ["list_tools"]
|
||||
# only list_tools will be available
|
||||
```
|
||||
|
||||
**Use this when:**
|
||||
- You want strict control over which tools are available
|
||||
- You're in a high-security environment
|
||||
- You're testing a new MCP server with limited tools
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="blocked" label="Block Specific Tools">
|
||||
|
||||
Use `disallowed_tools` to block specific tools. All other tools will be available.
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
mcp_servers:
|
||||
github_mcp:
|
||||
url: "https://api.githubcopilot.com/mcp"
|
||||
auth_type: oauth2
|
||||
authorization_url: https://github.com/login/oauth/authorize
|
||||
token_url: https://github.com/login/oauth/access_token
|
||||
client_id: os.environ/GITHUB_OAUTH_CLIENT_ID
|
||||
client_secret: os.environ/GITHUB_OAUTH_CLIENT_SECRET
|
||||
scopes: ["public_repo", "user:email"]
|
||||
disallowed_tools: ["repo_delete"]
|
||||
# only repo_delete will be blocked
|
||||
```
|
||||
|
||||
**Use this when:**
|
||||
- Most tools are safe, but you want to block a few dangerous ones
|
||||
- You want to prevent expensive API calls
|
||||
- You're gradually adding restrictions to an existing server
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Important Notes
|
||||
|
||||
- If you specify both `allowed_tools` and `disallowed_tools`, the allowed list takes priority
|
||||
- Tool names are case-sensitive
|
||||
|
||||
---
|
||||
|
||||
## Allow/Disallow MCP Tool Parameters
|
||||
|
||||
Control which parameters are allowed for specific MCP tools using the `allowed_params` configuration. This provides fine-grained control over tool usage by restricting the parameters that can be passed to each tool.
|
||||
|
||||
### Configuration
|
||||
|
||||
`allowed_params` is a dictionary that maps tool names to lists of allowed parameter names. When configured, only the specified parameters will be accepted for that tool - any other parameters will be rejected with a 403 error.
|
||||
|
||||
```yaml title="config.yaml with allowed_params" showLineNumbers
|
||||
mcp_servers:
|
||||
deepwiki_mcp:
|
||||
url: https://mcp.deepwiki.com/mcp
|
||||
transport: "http"
|
||||
auth_type: "none"
|
||||
allowed_params:
|
||||
# Tool name: list of allowed parameters
|
||||
read_wiki_contents: ["status"]
|
||||
|
||||
my_api_mcp:
|
||||
url: "https://my-api-server.com"
|
||||
auth_type: "api_key"
|
||||
auth_value: "my-key"
|
||||
allowed_params:
|
||||
# Using unprefixed tool name
|
||||
getpetbyid: ["status"]
|
||||
# Using prefixed tool name (both formats work)
|
||||
my_api_mcp-findpetsbystatus: ["status", "limit"]
|
||||
# Another tool with multiple allowed params
|
||||
create_issue: ["title", "body", "labels"]
|
||||
```
|
||||
|
||||
### How It Works
|
||||
|
||||
1. **Tool-specific filtering**: Each tool can have its own list of allowed parameters
|
||||
2. **Flexible naming**: Tool names can be specified with or without the server prefix (e.g., both `"getpetbyid"` and `"my_api_mcp-getpetbyid"` work)
|
||||
3. **Whitelist approach**: Only parameters in the allowed list are permitted
|
||||
4. **Unlisted tools**: If `allowed_params` is not set, all parameters are allowed
|
||||
5. **Error handling**: Requests with disallowed parameters receive a 403 error with details about which parameters are allowed
|
||||
|
||||
### Example Request Behavior
|
||||
|
||||
With the configuration above, here's how requests would be handled:
|
||||
|
||||
**✅ Allowed Request:**
|
||||
```json
|
||||
{
|
||||
"tool": "read_wiki_contents",
|
||||
"arguments": {
|
||||
"status": "active"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**❌ Rejected Request:**
|
||||
```json
|
||||
{
|
||||
"tool": "read_wiki_contents",
|
||||
"arguments": {
|
||||
"status": "active",
|
||||
"limit": 10 // This parameter is not allowed
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Error Response:**
|
||||
```json
|
||||
{
|
||||
"error": "Parameters ['limit'] are not allowed for tool read_wiki_contents. Allowed parameters: ['status']. Contact proxy admin to allow these parameters."
|
||||
}
|
||||
```
|
||||
|
||||
### Use Cases
|
||||
|
||||
- **Security**: Prevent users from accessing sensitive parameters or dangerous operations
|
||||
- **Cost control**: Restrict expensive parameters (e.g., limiting result counts)
|
||||
- **Compliance**: Enforce parameter usage policies for regulatory requirements
|
||||
- **Staged rollouts**: Gradually enable parameters as tools are tested
|
||||
- **Multi-tenant isolation**: Different parameter access for different user groups
|
||||
|
||||
### Combining with Tool Filtering
|
||||
|
||||
`allowed_params` works alongside `allowed_tools` and `disallowed_tools` for complete control:
|
||||
|
||||
```yaml title="Combined filtering example" showLineNumbers
|
||||
mcp_servers:
|
||||
github_mcp:
|
||||
url: "https://api.githubcopilot.com/mcp"
|
||||
auth_type: oauth2
|
||||
authorization_url: https://github.com/login/oauth/authorize
|
||||
token_url: https://github.com/login/oauth/access_token
|
||||
client_id: os.environ/GITHUB_OAUTH_CLIENT_ID
|
||||
client_secret: os.environ/GITHUB_OAUTH_CLIENT_SECRET
|
||||
scopes: ["public_repo", "user:email"]
|
||||
# Only allow specific tools
|
||||
allowed_tools: ["create_issue", "list_issues", "search_issues"]
|
||||
# Block dangerous operations
|
||||
disallowed_tools: ["delete_repo"]
|
||||
# Restrict parameters per tool
|
||||
allowed_params:
|
||||
create_issue: ["title", "body", "labels"]
|
||||
list_issues: ["state", "sort", "perPage"]
|
||||
search_issues: ["query", "sort", "order", "perPage"]
|
||||
```
|
||||
|
||||
This configuration ensures that:
|
||||
1. Only the three listed tools are available
|
||||
2. The `delete_repo` tool is explicitly blocked
|
||||
3. Each tool can only use its specified parameters
|
||||
|
||||
---
|
||||
|
||||
## MCP Server Access Control
|
||||
|
||||
LiteLLM Proxy provides two methods for controlling access to specific MCP servers:
|
||||
|
||||
1. **URL-based Namespacing** - Use URL paths to directly access specific servers or access groups
|
||||
2. **Header-based Namespacing** - Use the `x-mcp-servers` header to specify which servers to access
|
||||
|
||||
---
|
||||
|
||||
### Method 1: URL-based Namespacing
|
||||
|
||||
LiteLLM Proxy supports URL-based namespacing for MCP servers using the format `/<servers or access groups>/mcp`. This allows you to:
|
||||
|
||||
- **Direct URL Access**: Point MCP clients directly to specific servers or access groups via URL
|
||||
- **Simplified Configuration**: Use URLs instead of headers for server selection
|
||||
- **Access Group Support**: Use access group names in URLs for grouped server access
|
||||
|
||||
#### URL Format
|
||||
|
||||
```
|
||||
<your-litellm-proxy-base-url>/<server_alias_or_access_group>/mcp
|
||||
```
|
||||
|
||||
**Examples:**
|
||||
- `/github_mcp/mcp` - Access tools from the "github_mcp" MCP server
|
||||
- `/zapier/mcp` - Access tools from the "zapier" MCP server
|
||||
- `/dev_group/mcp` - Access tools from all servers in the "dev_group" access group
|
||||
- `/github_mcp,zapier/mcp` - Access tools from multiple specific servers
|
||||
|
||||
#### Usage Examples
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="openai" label="OpenAI API">
|
||||
|
||||
```bash title="cURL Example with URL Namespacing" showLineNumbers
|
||||
curl --location 'https://api.openai.com/v1/responses' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header "Authorization: Bearer $OPENAI_API_KEY" \
|
||||
--data '{
|
||||
"model": "gpt-4o",
|
||||
"tools": [
|
||||
{
|
||||
"type": "mcp",
|
||||
"server_label": "litellm",
|
||||
"server_url": "<your-litellm-proxy-base-url>/github_mcp/mcp",
|
||||
"require_approval": "never",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer YOUR_LITELLM_API_KEY"
|
||||
}
|
||||
}
|
||||
],
|
||||
"input": "Run available tools",
|
||||
"tool_choice": "required"
|
||||
}'
|
||||
```
|
||||
|
||||
This example uses URL namespacing to access only the "github" MCP server.
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="litellm" label="LiteLLM Proxy">
|
||||
|
||||
```bash title="cURL Example with URL Namespacing" showLineNumbers
|
||||
curl --location '<your-litellm-proxy-base-url>/v1/responses' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header "Authorization: Bearer $LITELLM_API_KEY" \
|
||||
--data '{
|
||||
"model": "gpt-4o",
|
||||
"tools": [
|
||||
{
|
||||
"type": "mcp",
|
||||
"server_label": "litellm",
|
||||
"server_url": "<your-litellm-proxy-base-url>/dev_group/mcp",
|
||||
"require_approval": "never",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer YOUR_LITELLM_API_KEY"
|
||||
}
|
||||
}
|
||||
],
|
||||
"input": "Run available tools",
|
||||
"tool_choice": "required"
|
||||
}'
|
||||
```
|
||||
|
||||
This example uses URL namespacing to access all servers in the "dev_group" access group.
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="cursor" label="Cursor IDE">
|
||||
|
||||
```json title="Cursor MCP Configuration with URL Namespacing" showLineNumbers
|
||||
{
|
||||
"mcpServers": {
|
||||
"LiteLLM": {
|
||||
"url": "<your-litellm-proxy-base-url>/github_mcp,zapier/mcp",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer $LITELLM_API_KEY"
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
This configuration uses URL namespacing to access tools from both "github" and "zapier" MCP servers.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
#### Benefits of URL Namespacing
|
||||
|
||||
- **Direct Access**: No need for additional headers to specify servers
|
||||
- **Clean URLs**: Self-documenting URLs that clearly indicate which servers are accessible
|
||||
- **Access Group Support**: Use access group names for grouped server access
|
||||
- **Multiple Servers**: Specify multiple servers in a single URL with comma separation
|
||||
- **Simplified Configuration**: Easier setup for MCP clients that prefer URL-based configuration
|
||||
|
||||
---
|
||||
|
||||
### Method 2: Header-based Namespacing
|
||||
|
||||
You can choose to access specific MCP servers and only list their tools using the `x-mcp-servers` header. This header allows you to:
|
||||
- Limit tool access to one or more specific MCP servers
|
||||
- Control which tools are available in different environments or use cases
|
||||
|
||||
The header accepts a comma-separated list of server aliases: `"alias_1,Server2,Server3"`
|
||||
|
||||
**Notes:**
|
||||
- If the header is not provided, tools from all available MCP servers will be accessible
|
||||
- This method works with the standard LiteLLM MCP endpoint
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="openai" label="OpenAI API">
|
||||
|
||||
```bash title="cURL Example with Header Namespacing" showLineNumbers
|
||||
curl --location 'https://api.openai.com/v1/responses' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header "Authorization: Bearer $OPENAI_API_KEY" \
|
||||
--data '{
|
||||
"model": "gpt-4o",
|
||||
"tools": [
|
||||
{
|
||||
"type": "mcp",
|
||||
"server_label": "litellm",
|
||||
"server_url": "<your-litellm-proxy-base-url>/mcp/",
|
||||
"require_approval": "never",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer YOUR_LITELLM_API_KEY",
|
||||
"x-mcp-servers": "alias_1"
|
||||
}
|
||||
}
|
||||
],
|
||||
"input": "Run available tools",
|
||||
"tool_choice": "required"
|
||||
}'
|
||||
```
|
||||
|
||||
In this example, the request will only have access to tools from the "alias_1" MCP server.
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="litellm" label="LiteLLM Proxy">
|
||||
|
||||
```bash title="cURL Example with Header Namespacing" showLineNumbers
|
||||
curl --location '<your-litellm-proxy-base-url>/v1/responses' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header "Authorization: Bearer $LITELLM_API_KEY" \
|
||||
--data '{
|
||||
"model": "gpt-4o",
|
||||
"tools": [
|
||||
{
|
||||
"type": "mcp",
|
||||
"server_label": "litellm",
|
||||
"server_url": "<your-litellm-proxy-base-url>/mcp/",
|
||||
"require_approval": "never",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer YOUR_LITELLM_API_KEY",
|
||||
"x-mcp-servers": "alias_1,Server2"
|
||||
}
|
||||
}
|
||||
],
|
||||
"input": "Run available tools",
|
||||
"tool_choice": "required"
|
||||
}'
|
||||
```
|
||||
|
||||
This configuration restricts the request to only use tools from the specified MCP servers.
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="cursor" label="Cursor IDE">
|
||||
|
||||
```json title="Cursor MCP Configuration with Header Namespacing" showLineNumbers
|
||||
{
|
||||
"mcpServers": {
|
||||
"LiteLLM": {
|
||||
"url": "<your-litellm-proxy-base-url>/mcp/",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer $LITELLM_API_KEY",
|
||||
"x-mcp-servers": "alias_1,Server2"
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
This configuration in Cursor IDE settings will limit tool access to only the specified MCP servers.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
---
|
||||
|
||||
### Comparison: Header vs URL Namespacing
|
||||
|
||||
| Feature | Header Namespacing | URL Namespacing |
|
||||
|---------|-------------------|-----------------|
|
||||
| **Method** | Uses `x-mcp-servers` header | Uses URL path `/<servers>/mcp` |
|
||||
| **Endpoint** | Standard `litellm_proxy` endpoint | Custom `/<servers>/mcp` endpoint |
|
||||
| **Configuration** | Requires additional header | Self-contained in URL |
|
||||
| **Multiple Servers** | Comma-separated in header | Comma-separated in URL path |
|
||||
| **Access Groups** | Supported via header | Supported via URL path |
|
||||
| **Client Support** | Works with all MCP clients | Works with URL-aware MCP clients |
|
||||
| **Use Case** | Dynamic server selection | Fixed server configuration |
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="openai" label="OpenAI API">
|
||||
|
||||
```bash title="cURL Example with Server Segregation" showLineNumbers
|
||||
curl --location 'https://api.openai.com/v1/responses' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header "Authorization: Bearer $OPENAI_API_KEY" \
|
||||
--data '{
|
||||
"model": "gpt-4o",
|
||||
"tools": [
|
||||
{
|
||||
"type": "mcp",
|
||||
"server_label": "litellm",
|
||||
"server_url": "<your-litellm-proxy-base-url>/mcp/",
|
||||
"require_approval": "never",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer YOUR_LITELLM_API_KEY",
|
||||
"x-mcp-servers": "alias_1"
|
||||
}
|
||||
}
|
||||
],
|
||||
"input": "Run available tools",
|
||||
"tool_choice": "required"
|
||||
}'
|
||||
```
|
||||
|
||||
In this example, the request will only have access to tools from the "alias_1" MCP server.
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="litellm" label="LiteLLM Proxy">
|
||||
|
||||
```bash title="cURL Example with Server Segregation" showLineNumbers
|
||||
curl --location '<your-litellm-proxy-base-url>/v1/responses' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header "Authorization: Bearer $LITELLM_API_KEY" \
|
||||
--data '{
|
||||
"model": "gpt-4o",
|
||||
"tools": [
|
||||
{
|
||||
"type": "mcp",
|
||||
"server_label": "litellm",
|
||||
"server_url": "litellm_proxy",
|
||||
"require_approval": "never",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer YOUR_LITELLM_API_KEY",
|
||||
"x-mcp-servers": "alias_1,Server2"
|
||||
}
|
||||
}
|
||||
],
|
||||
"input": "Run available tools",
|
||||
"tool_choice": "required"
|
||||
}'
|
||||
```
|
||||
|
||||
This configuration restricts the request to only use tools from the specified MCP servers.
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="cursor" label="Cursor IDE">
|
||||
|
||||
```json title="Cursor MCP Configuration with Server Segregation" showLineNumbers
|
||||
{
|
||||
"mcpServers": {
|
||||
"LiteLLM": {
|
||||
"url": "litellm_proxy",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer $LITELLM_API_KEY",
|
||||
"x-mcp-servers": "alias_1,Server2"
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
This configuration in Cursor IDE settings will limit tool access to only the specified MCP server.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Grouping MCPs (Access Groups)
|
||||
|
||||
MCP Access Groups allow you to group multiple MCP servers together for easier management.
|
||||
|
||||
#### 1. Create an Access Group
|
||||
|
||||
##### A. Creating Access Groups using Config:
|
||||
|
||||
```yaml title="Creating access groups for MCP using the config" showLineNumbers
|
||||
mcp_servers:
|
||||
"deepwiki_mcp":
|
||||
url: https://mcp.deepwiki.com/mcp
|
||||
transport: "http"
|
||||
auth_type: "none"
|
||||
access_groups: ["dev_group"]
|
||||
```
|
||||
|
||||
While adding `mcp_servers` using the config:
|
||||
- Pass in a list of strings inside `access_groups`
|
||||
- These groups can then be used for segregating access using keys, teams and MCP clients using headers
|
||||
|
||||
##### B. Creating Access Groups using UI
|
||||
|
||||
To create an access group:
|
||||
- Go to MCP Servers in the LiteLLM UI
|
||||
- Click "Add a New MCP Server"
|
||||
- Under "MCP Access Groups", create a new group (e.g., "dev_group") by typing it
|
||||
- Add the same group name to other servers to group them together
|
||||
|
||||
<Image
|
||||
img={require('../img/mcp_create_access_group.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0'}}
|
||||
/>
|
||||
|
||||
#### 2. Use Access Group in Cursor
|
||||
|
||||
Include the access group name in the `x-mcp-servers` header:
|
||||
|
||||
```json title="Cursor Configuration with Access Groups" showLineNumbers
|
||||
{
|
||||
"mcpServers": {
|
||||
"LiteLLM": {
|
||||
"url": "litellm_proxy",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer $LITELLM_API_KEY",
|
||||
"x-mcp-servers": "dev_group"
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
This gives you access to all servers in the "dev_group" access group.
|
||||
- Which means that if deepwiki server (and any other servers) which have the access group `dev_group` assigned to them will be available for tool calling
|
||||
|
||||
#### Advanced: Connecting Access Groups to API Keys
|
||||
|
||||
When creating API keys, you can assign them to specific access groups for permission management:
|
||||
|
||||
- Go to "Keys" in the LiteLLM UI and click "Create Key"
|
||||
- Select the desired MCP access groups from the dropdown
|
||||
- The key will have access to all MCP servers in those groups
|
||||
- This is reflected in the Test Key page
|
||||
|
||||
<Image
|
||||
img={require('../img/mcp_key_access_group.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0'}}
|
||||
/>
|
||||
|
||||
|
||||
|
||||
## Set Allowed Tools for a Key, Team, or Organization
|
||||
|
||||
Control which tools different teams can access from the same MCP server. For example, give your Engineering team access to `list_repositories`, `create_issue`, and `search_code`, while Sales only gets `search_code` and `close_issue`.
|
||||
|
|
|
|||
|
|
@ -7,13 +7,6 @@ import TabItem from '@theme/TabItem';
|
|||
|
||||
AI Observability and Evaluation Platform
|
||||
|
||||
:::tip
|
||||
|
||||
This is community maintained, Please make an issue if you run into a bug
|
||||
https://github.com/BerriAI/litellm
|
||||
|
||||
:::
|
||||
|
||||
<Image img={require('../../img/arize.png')} />
|
||||
|
||||
|
||||
|
|
@ -53,7 +46,7 @@ response = litellm.completion(
|
|||
)
|
||||
```
|
||||
|
||||
### Using with LiteLLM Proxy
|
||||
## Using with LiteLLM Proxy
|
||||
|
||||
1. Setup config.yaml
|
||||
```yaml
|
||||
|
|
@ -71,7 +64,7 @@ general_settings:
|
|||
master_key: "sk-1234" # can also be set as an environment variable
|
||||
|
||||
environment_variables:
|
||||
ARIZE_SPACE_KEY: "d0*****"
|
||||
ARIZE_SPACE_ID: "d0*****"
|
||||
ARIZE_API_KEY: "141a****"
|
||||
ARIZE_ENDPOINT: "https://otlp.arize.com/v1" # OPTIONAL - your custom arize GRPC api endpoint
|
||||
ARIZE_HTTP_ENDPOINT: "https://otlp.arize.com/v1" # OPTIONAL - your custom arize HTTP api endpoint. Set either this or ARIZE_ENDPOINT or Neither (defaults to https://otlp.arize.com/v1 on grpc)
|
||||
|
|
@ -96,7 +89,8 @@ curl -X POST 'http://0.0.0.0:4000/chat/completions' \
|
|||
|
||||
Supported parameters:
|
||||
- `arize_api_key`
|
||||
- `arize_space_key`
|
||||
- `arize_space_key` *(deprecated, use `arize_space_id` instead)*
|
||||
- `arize_space_id`
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
|
@ -117,8 +111,8 @@ response = litellm.completion(
|
|||
messages=[
|
||||
{"role": "user", "content": "Hi 👋 - i'm openai"}
|
||||
],
|
||||
arize_api_key=os.getenv("ARIZE_SPACE_2_API_KEY"),
|
||||
arize_space_key=os.getenv("ARIZE_SPACE_2_KEY"),
|
||||
arize_api_key=os.getenv("ARIZE_API_KEY"),
|
||||
arize_space_id=os.getenv("ARIZE_SPACE_ID"),
|
||||
)
|
||||
```
|
||||
|
||||
|
|
@ -159,8 +153,8 @@ curl -X POST 'http://0.0.0.0:4000/chat/completions' \
|
|||
-d '{
|
||||
"model": "gpt-4",
|
||||
"messages": [{"role": "user", "content": "Hi 👋 - i'm openai"}],
|
||||
"arize_api_key": "ARIZE_SPACE_2_API_KEY",
|
||||
"arize_space_key": "ARIZE_SPACE_2_KEY"
|
||||
"arize_api_key": "ARIZE_API_KEY",
|
||||
"arize_space_id": "ARIZE_SPACE_ID"
|
||||
}'
|
||||
```
|
||||
</TabItem>
|
||||
|
|
@ -183,8 +177,8 @@ response = client.chat.completions.create(
|
|||
}
|
||||
],
|
||||
extra_body={
|
||||
"arize_api_key": "ARIZE_SPACE_2_API_KEY",
|
||||
"arize_space_key": "ARIZE_SPACE_2_KEY"
|
||||
"arize_api_key": "ARIZE_API_KEY",
|
||||
"arize_space_id": "ARIZE_SPACE_ID"
|
||||
}
|
||||
)
|
||||
|
||||
|
|
@ -199,5 +193,5 @@ print(response)
|
|||
|
||||
- [Schedule Demo 👋](https://calendly.com/d/4mp-gd3-k5k/berriai-1-1-onboarding-litellm-hosted-version)
|
||||
- [Community Discord 💭](https://discord.gg/wuPM9dRgDw)
|
||||
- Our numbers 📞 +1 (770) 8783-106 / +1 (412) 618-6238
|
||||
- Our numbers 📞 +1 (770) 8783-106 / +1 (412) 618-6238
|
||||
- Our emails ✉️ ishaan@berri.ai / krrish@berri.ai
|
||||
|
|
|
|||
|
|
@ -203,7 +203,11 @@ asyncio.run(test_chat_openai())
|
|||
|
||||
## What's Available in kwargs?
|
||||
|
||||
The kwargs dictionary contains all the details about your API call:
|
||||
The kwargs dictionary contains all the details about your API call.
|
||||
|
||||
:::info
|
||||
For the complete logging payload specification, see the [Standard Logging Payload Spec](https://docs.litellm.ai/docs/proxy/logging_spec).
|
||||
:::
|
||||
|
||||
```python
|
||||
def custom_callback(kwargs, completion_response, start_time, end_time):
|
||||
|
|
|
|||
|
|
@ -71,17 +71,19 @@ DD_SOURCE="litellm_dev" # [OPTIONAL] your datadog source. use to different
|
|||
Send logs through a local DataDog agent (useful for containerized environments):
|
||||
|
||||
```shell
|
||||
DD_AGENT_HOST="localhost" # hostname or IP of DataDog agent
|
||||
DD_AGENT_PORT="10518" # [OPTIONAL] port of DataDog agent (default: 10518)
|
||||
DD_API_KEY="5f2d0f310***********" # [OPTIONAL] your datadog API Key (agent handles auth)
|
||||
DD_SOURCE="litellm_dev" # [OPTIONAL] your datadog source
|
||||
LITELLM_DD_AGENT_HOST="localhost" # hostname or IP of DataDog agent
|
||||
LITELLM_DD_AGENT_PORT="10518" # [OPTIONAL] port of DataDog agent (default: 10518)
|
||||
DD_API_KEY="5f2d0f310***********" # [OPTIONAL] your datadog API Key (agent handles auth)
|
||||
DD_SOURCE="litellm_dev" # [OPTIONAL] your datadog source
|
||||
```
|
||||
|
||||
When `DD_AGENT_HOST` is set, logs are sent to the agent instead of directly to DataDog API. This is useful for:
|
||||
When `LITELLM_DD_AGENT_HOST` is set, logs are sent to the agent instead of directly to DataDog API. This is useful for:
|
||||
- Centralized log shipping in containerized environments
|
||||
- Reducing direct API calls from multiple services
|
||||
- Leveraging agent-side processing and filtering
|
||||
|
||||
**Note:** We use `LITELLM_DD_AGENT_HOST` instead of `DD_AGENT_HOST` to avoid conflicts with `ddtrace` which automatically sets `DD_AGENT_HOST` for APM tracing.
|
||||
|
||||
**Step 3**: Start the proxy, make a test request
|
||||
|
||||
Start proxy
|
||||
|
|
@ -191,8 +193,8 @@ LiteLLM supports customizing the following Datadog environment variables
|
|||
|---------------------|-------------|---------------|----------|
|
||||
| `DD_API_KEY` | Your Datadog API key for authentication (required for direct API, optional for agent) | None | Conditional* |
|
||||
| `DD_SITE` | Your Datadog site (e.g., "us5.datadoghq.com") (required for direct API) | None | Conditional* |
|
||||
| `DD_AGENT_HOST` | Hostname or IP of DataDog agent (e.g., "localhost"). When set, logs are sent to agent instead of direct API | None | ❌ No |
|
||||
| `DD_AGENT_PORT` | Port of DataDog agent for log intake | "10518" | ❌ No |
|
||||
| `LITELLM_DD_AGENT_HOST` | Hostname or IP of DataDog agent (e.g., "localhost"). When set, logs are sent to agent instead of direct API | None | ❌ No |
|
||||
| `LITELLM_DD_AGENT_PORT` | Port of DataDog agent for log intake | "10518" | ❌ No |
|
||||
| `DD_ENV` | Environment tag for your logs (e.g., "production", "staging") | "unknown" | ❌ No |
|
||||
| `DD_SERVICE` | Service name for your logs | "litellm-server" | ❌ No |
|
||||
| `DD_SOURCE` | Source name for your logs | "litellm" | ❌ No |
|
||||
|
|
@ -201,5 +203,5 @@ LiteLLM supports customizing the following Datadog environment variables
|
|||
| `POD_NAME` | Pod name tag (useful for Kubernetes deployments) | "unknown" | ❌ No |
|
||||
|
||||
\* **Required when using Direct API** (default): `DD_API_KEY` and `DD_SITE` are required
|
||||
\* **Optional when using DataDog Agent**: Set `DD_AGENT_HOST` to use agent mode; `DD_API_KEY` and `DD_SITE` are not required
|
||||
\* **Optional when using DataDog Agent**: Set `LITELLM_DD_AGENT_HOST` to use agent mode; `DD_API_KEY` and `DD_SITE` are not required
|
||||
|
||||
|
|
|
|||
110
docs/my-website/docs/observability/generic_api.md
Normal file
110
docs/my-website/docs/observability/generic_api.md
Normal file
|
|
@ -0,0 +1,110 @@
|
|||
# Generic API Callback (Webhook)
|
||||
|
||||
Send LiteLLM logs to any HTTP endpoint.
|
||||
|
||||
## Quick Start
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-3.5-turbo
|
||||
litellm_params:
|
||||
model: openai/gpt-3.5-turbo
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
litellm_settings:
|
||||
callbacks: ["custom_api_name"]
|
||||
|
||||
callback_settings:
|
||||
custom_api_name:
|
||||
callback_type: generic_api
|
||||
endpoint: https://your-endpoint.com/logs
|
||||
headers:
|
||||
Authorization: Bearer sk-1234
|
||||
```
|
||||
|
||||
## Configuration
|
||||
|
||||
### Basic Setup
|
||||
|
||||
```yaml
|
||||
callback_settings:
|
||||
<callback_name>:
|
||||
callback_type: generic_api
|
||||
endpoint: https://your-endpoint.com # required
|
||||
headers: # optional
|
||||
Authorization: Bearer <token>
|
||||
Custom-Header: value
|
||||
event_types: # optional, defaults to all events
|
||||
- llm_api_success
|
||||
- llm_api_failure
|
||||
```
|
||||
|
||||
### Parameters
|
||||
|
||||
| Parameter | Type | Required | Description |
|
||||
|-----------|------|----------|-------------|
|
||||
| `callback_type` | string | Yes | Must be `generic_api` |
|
||||
| `endpoint` | string | Yes | HTTP endpoint to send logs to |
|
||||
| `headers` | dict | No | Custom headers for the request |
|
||||
| `event_types` | list | No | Filter events: `llm_api_success`, `llm_api_failure`. Defaults to all events. |
|
||||
|
||||
## Pre-configured Callbacks
|
||||
|
||||
Use built-in configurations from `generic_api_compatible_callbacks.json`:
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
callbacks: ["rubrik"] # loads pre-configured settings
|
||||
|
||||
callback_settings:
|
||||
rubrik:
|
||||
callback_type: generic_api
|
||||
endpoint: https://your-endpoint.com # override defaults
|
||||
headers:
|
||||
Authorization: Bearer ${RUBRIK_API_KEY}
|
||||
```
|
||||
|
||||
## Payload Format
|
||||
|
||||
Logs are sent as `StandardLoggingPayload` [objects](https://docs.litellm.ai/docs/proxy/logging_spec) in JSON format:
|
||||
|
||||
```json
|
||||
[
|
||||
{
|
||||
"id": "chatcmpl-123",
|
||||
"call_type": "litellm.completion",
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [...],
|
||||
"response": {...},
|
||||
"usage": {...},
|
||||
"cost": 0.0001,
|
||||
"startTime": "2024-01-01T00:00:00",
|
||||
"endTime": "2024-01-01T00:00:01",
|
||||
"metadata": {...}
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
## Environment Variables
|
||||
|
||||
Set via environment variables instead of config:
|
||||
|
||||
```bash
|
||||
export GENERIC_LOGGER_ENDPOINT=https://your-endpoint.com
|
||||
export GENERIC_LOGGER_HEADERS="Authorization=Bearer token,Custom-Header=value"
|
||||
```
|
||||
|
||||
## Batch Settings
|
||||
|
||||
Control batching behavior (inherits from `CustomBatchLogger`):
|
||||
|
||||
```yaml
|
||||
callback_settings:
|
||||
my_api:
|
||||
callback_type: generic_api
|
||||
endpoint: https://your-endpoint.com
|
||||
batch_size: 100 # default: 100
|
||||
flush_interval: 60 # seconds, default: 60
|
||||
```
|
||||
|
||||
|
||||
|
|
@ -10,7 +10,7 @@ https://github.com/BerriAI/litellm
|
|||
|
||||
:::
|
||||
|
||||
[Helicone](https://helicone.ai/) is an open source observability platform that proxies your LLM requests and provides key insights into your usage, spend, latency and more.
|
||||
[Helicone](https://helicone.ai/) is an open sourced observability platform providing key insights into your usage, spend, latency and more.
|
||||
|
||||
## Quick Start
|
||||
|
||||
|
|
@ -25,14 +25,10 @@ from litellm import completion
|
|||
|
||||
## Set env variables
|
||||
os.environ["HELICONE_API_KEY"] = "your-helicone-key"
|
||||
os.environ["OPENAI_API_KEY"] = "your-openai-key"
|
||||
|
||||
# Set callbacks
|
||||
litellm.success_callback = ["helicone"]
|
||||
|
||||
# OpenAI call
|
||||
response = completion(
|
||||
model="gpt-4o",
|
||||
model="helicone/gpt-4o-mini",
|
||||
messages=[{"role": "user", "content": "Hi 👋 - I'm OpenAI"}],
|
||||
)
|
||||
|
||||
|
|
@ -54,7 +50,7 @@ model_list:
|
|||
# Add Helicone callback
|
||||
litellm_settings:
|
||||
success_callback: ["helicone"]
|
||||
|
||||
|
||||
# Set Helicone API key
|
||||
environment_variables:
|
||||
HELICONE_API_KEY: "your-helicone-key"
|
||||
|
|
@ -72,12 +68,12 @@ litellm --config config.yaml
|
|||
|
||||
There are two main approaches to integrate Helicone with LiteLLM:
|
||||
|
||||
1. **Callbacks**: Log to Helicone while using any provider
|
||||
2. **Proxy Mode**: Use Helicone as a proxy for advanced features
|
||||
1. **As a Provider**: Use Helicone to log requests for [all models supported ](../providers/helicone)
|
||||
2. **Callbacks**: Log to Helicone while using any provider
|
||||
|
||||
### Supported LLM Providers
|
||||
|
||||
Helicone can log requests across [various LLM providers](https://docs.helicone.ai/getting-started/quick-start), including:
|
||||
Helicone can log requests across [all major LLM providers](https://helicone.ai/models), including:
|
||||
|
||||
- OpenAI
|
||||
- Azure
|
||||
|
|
@ -88,156 +84,149 @@ Helicone can log requests across [various LLM providers](https://docs.helicone.a
|
|||
- Replicate
|
||||
- And more
|
||||
|
||||
## Method 1: Using Callbacks
|
||||
## Method 1: Using Helicone as a Provider
|
||||
|
||||
Helicone's AI Gateway provides [advanced functionality](https://docs.helicone.ai) like caching, rate limiting, LLM security, and more.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="Python SDK">
|
||||
|
||||
Set Helicone as your base URL and pass authentication headers:
|
||||
|
||||
```python
|
||||
import os
|
||||
import litellm
|
||||
from litellm import completion
|
||||
|
||||
os.environ["HELICONE_API_KEY"] = "" # your Helicone API key
|
||||
|
||||
messages = [{"content": "What is the capital of France?", "role": "user"}]
|
||||
|
||||
# Helicone call - routes through Helicone gateway to any model
|
||||
response = completion(
|
||||
model="helicone/gpt-4o-mini", # or any 100+ models
|
||||
messages=messages
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
### Advanced Usage
|
||||
|
||||
You can add custom metadata and properties to your requests using Helicone headers. Here are some examples:
|
||||
|
||||
```python
|
||||
litellm.metadata = {
|
||||
"Helicone-User-Id": "user-abc", # Specify the user making the request
|
||||
"Helicone-Property-App": "web", # Custom property to add additional information
|
||||
"Helicone-Property-Custom": "any-value", # Add any custom property
|
||||
"Helicone-Prompt-Id": "prompt-supreme-court", # Assign an ID to associate this prompt with future versions
|
||||
"Helicone-Cache-Enabled": "true", # Enable caching of responses
|
||||
"Cache-Control": "max-age=3600", # Set cache limit to 1 hour
|
||||
"Helicone-RateLimit-Policy": "10;w=60;s=user", # Set rate limit policy
|
||||
"Helicone-Retry-Enabled": "true", # Enable retry mechanism
|
||||
"helicone-retry-num": "3", # Set number of retries
|
||||
"helicone-retry-factor": "2", # Set exponential backoff factor
|
||||
"Helicone-Model-Override": "gpt-3.5-turbo-0613", # Override the model used for cost calculation
|
||||
"Helicone-Session-Id": "session-abc-123", # Set session ID for tracking
|
||||
"Helicone-Session-Path": "parent-trace/child-trace", # Set session path for hierarchical tracking
|
||||
"Helicone-Omit-Response": "false", # Include response in logging (default behavior)
|
||||
"Helicone-Omit-Request": "false", # Include request in logging (default behavior)
|
||||
"Helicone-LLM-Security-Enabled": "true", # Enable LLM security features
|
||||
"Helicone-Moderations-Enabled": "true", # Enable content moderation
|
||||
}
|
||||
```
|
||||
|
||||
### Caching and Rate Limiting
|
||||
|
||||
Enable caching and set up rate limiting policies:
|
||||
|
||||
```python
|
||||
litellm.metadata = {
|
||||
"Helicone-Cache-Enabled": "true", # Enable caching of responses
|
||||
"Cache-Control": "max-age=3600", # Set cache limit to 1 hour
|
||||
"Helicone-RateLimit-Policy": "100;w=3600;s=user", # Set rate limit policy
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Method 2: Using Callbacks
|
||||
|
||||
Log requests to Helicone while using any LLM provider directly.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="Python SDK">
|
||||
<TabItem value="sdk" label="Python SDK">
|
||||
|
||||
```python
|
||||
import os
|
||||
import litellm
|
||||
from litellm import completion
|
||||
```python
|
||||
import os
|
||||
import litellm
|
||||
from litellm import completion
|
||||
|
||||
## Set env variables
|
||||
os.environ["HELICONE_API_KEY"] = "your-helicone-key"
|
||||
os.environ["OPENAI_API_KEY"] = "your-openai-key"
|
||||
# os.environ["HELICONE_API_BASE"] = "" # [OPTIONAL] defaults to `https://api.helicone.ai`
|
||||
## Set env variables
|
||||
os.environ["HELICONE_API_KEY"] = "your-helicone-key"
|
||||
os.environ["OPENAI_API_KEY"] = "your-openai-key"
|
||||
# os.environ["HELICONE_API_BASE"] = "" # [OPTIONAL] defaults to `https://api.helicone.ai`
|
||||
|
||||
# Set callbacks
|
||||
litellm.success_callback = ["helicone"]
|
||||
# Set callbacks
|
||||
litellm.success_callback = ["helicone"]
|
||||
|
||||
# OpenAI call
|
||||
response = completion(
|
||||
model="gpt-4o",
|
||||
messages=[{"role": "user", "content": "Hi 👋 - I'm OpenAI"}],
|
||||
)
|
||||
# OpenAI call
|
||||
response = completion(
|
||||
model="gpt-4o",
|
||||
messages=[{"role": "user", "content": "Hi 👋 - I'm OpenAI"}],
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
```yaml title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
- model_name: claude-3
|
||||
litellm_params:
|
||||
model: anthropic/claude-3-sonnet-20240229
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
```yaml title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
- model_name: claude-3
|
||||
litellm_params:
|
||||
model: anthropic/claude-3-sonnet-20240229
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
|
||||
# Add Helicone logging
|
||||
litellm_settings:
|
||||
success_callback: ["helicone"]
|
||||
|
||||
# Environment variables
|
||||
environment_variables:
|
||||
HELICONE_API_KEY: "your-helicone-key"
|
||||
OPENAI_API_KEY: "your-openai-key"
|
||||
ANTHROPIC_API_KEY: "your-anthropic-key"
|
||||
```
|
||||
# Add Helicone logging
|
||||
litellm_settings:
|
||||
success_callback: ["helicone"]
|
||||
|
||||
Start the proxy:
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
# Environment variables
|
||||
environment_variables:
|
||||
HELICONE_API_KEY: "your-helicone-key"
|
||||
OPENAI_API_KEY: "your-openai-key"
|
||||
ANTHROPIC_API_KEY: "your-anthropic-key"
|
||||
```
|
||||
|
||||
Make requests to your proxy:
|
||||
```python
|
||||
import openai
|
||||
Start the proxy:
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
client = openai.OpenAI(
|
||||
api_key="anything", # proxy doesn't require real API key
|
||||
base_url="http://localhost:4000"
|
||||
)
|
||||
Make requests to your proxy:
|
||||
```python
|
||||
import openai
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="gpt-4", # This gets logged to Helicone
|
||||
messages=[{"role": "user", "content": "Hello!"}]
|
||||
)
|
||||
```
|
||||
client = openai.OpenAI(
|
||||
api_key="anything", # proxy doesn't require real API key
|
||||
base_url="http://localhost:4000"
|
||||
)
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
response = client.chat.completions.create(
|
||||
model="gpt-4", # This gets logged to Helicone
|
||||
messages=[{"role": "user", "content": "Hello!"}]
|
||||
)
|
||||
```
|
||||
|
||||
## Method 2: Using Helicone as a Proxy
|
||||
|
||||
Helicone's proxy provides [advanced functionality](https://docs.helicone.ai/getting-started/proxy-vs-async) like caching, rate limiting, LLM security through [PromptArmor](https://promptarmor.com/) and more.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="Python SDK">
|
||||
|
||||
Set Helicone as your base URL and pass authentication headers:
|
||||
|
||||
```python
|
||||
import os
|
||||
import litellm
|
||||
from litellm import completion
|
||||
|
||||
# Configure LiteLLM to use Helicone proxy
|
||||
litellm.api_base = "https://oai.hconeai.com/v1"
|
||||
litellm.headers = {
|
||||
"Helicone-Auth": f"Bearer {os.getenv('HELICONE_API_KEY')}",
|
||||
}
|
||||
|
||||
# Set your OpenAI API key
|
||||
os.environ["OPENAI_API_KEY"] = "your-openai-key"
|
||||
|
||||
response = completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "How does a court case get to the Supreme Court?"}]
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
### Advanced Usage
|
||||
|
||||
You can add custom metadata and properties to your requests using Helicone headers. Here are some examples:
|
||||
|
||||
```python
|
||||
litellm.metadata = {
|
||||
"Helicone-Auth": f"Bearer {os.getenv('HELICONE_API_KEY')}", # Authenticate to send requests to Helicone API
|
||||
"Helicone-User-Id": "user-abc", # Specify the user making the request
|
||||
"Helicone-Property-App": "web", # Custom property to add additional information
|
||||
"Helicone-Property-Custom": "any-value", # Add any custom property
|
||||
"Helicone-Prompt-Id": "prompt-supreme-court", # Assign an ID to associate this prompt with future versions
|
||||
"Helicone-Cache-Enabled": "true", # Enable caching of responses
|
||||
"Cache-Control": "max-age=3600", # Set cache limit to 1 hour
|
||||
"Helicone-RateLimit-Policy": "10;w=60;s=user", # Set rate limit policy
|
||||
"Helicone-Retry-Enabled": "true", # Enable retry mechanism
|
||||
"helicone-retry-num": "3", # Set number of retries
|
||||
"helicone-retry-factor": "2", # Set exponential backoff factor
|
||||
"Helicone-Model-Override": "gpt-3.5-turbo-0613", # Override the model used for cost calculation
|
||||
"Helicone-Session-Id": "session-abc-123", # Set session ID for tracking
|
||||
"Helicone-Session-Path": "parent-trace/child-trace", # Set session path for hierarchical tracking
|
||||
"Helicone-Omit-Response": "false", # Include response in logging (default behavior)
|
||||
"Helicone-Omit-Request": "false", # Include request in logging (default behavior)
|
||||
"Helicone-LLM-Security-Enabled": "true", # Enable LLM security features
|
||||
"Helicone-Moderations-Enabled": "true", # Enable content moderation
|
||||
"Helicone-Fallbacks": '["gpt-3.5-turbo", "gpt-4"]', # Set fallback models
|
||||
}
|
||||
```
|
||||
|
||||
### Caching and Rate Limiting
|
||||
|
||||
Enable caching and set up rate limiting policies:
|
||||
|
||||
```python
|
||||
litellm.metadata = {
|
||||
"Helicone-Auth": f"Bearer {os.getenv('HELICONE_API_KEY')}", # Authenticate to send requests to Helicone API
|
||||
"Helicone-Cache-Enabled": "true", # Enable caching of responses
|
||||
"Cache-Control": "max-age=3600", # Set cache limit to 1 hour
|
||||
"Helicone-RateLimit-Policy": "100;w=3600;s=user", # Set rate limit policy
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Session Tracking and Tracing
|
||||
|
|
@ -245,57 +234,62 @@ litellm.metadata = {
|
|||
Track multi-step and agentic LLM interactions using session IDs and paths:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="Python SDK">
|
||||
<TabItem value="sdk" label="Python SDK">
|
||||
|
||||
```python
|
||||
import litellm
|
||||
```python
|
||||
import os
|
||||
import litellm
|
||||
from litellm import completion
|
||||
|
||||
litellm.api_base = "https://oai.hconeai.com/v1"
|
||||
litellm.metadata = {
|
||||
"Helicone-Auth": f"Bearer {os.getenv('HELICONE_API_KEY')}",
|
||||
"Helicone-Session-Id": "session-abc-123",
|
||||
"Helicone-Session-Path": "parent-trace/child-trace",
|
||||
}
|
||||
os.environ["HELICONE_API_KEY"] = "" # your Helicone API key
|
||||
|
||||
response = litellm.completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "Start a conversation"}]
|
||||
)
|
||||
```
|
||||
messages = [{"content": "What is the capital of France?", "role": "user"}]
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
response = completion(
|
||||
model="helicone/gpt-4",
|
||||
messages=messages,
|
||||
metadata={
|
||||
"Helicone-Session-Id": "session-abc-123",
|
||||
"Helicone-Session-Path": "parent-trace/child-trace",
|
||||
}
|
||||
)
|
||||
|
||||
```python
|
||||
import openai
|
||||
print(response)
|
||||
```
|
||||
|
||||
client = openai.OpenAI(
|
||||
api_key="anything",
|
||||
base_url="http://localhost:4000"
|
||||
)
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
# First request in session
|
||||
response1 = client.chat.completions.create(
|
||||
model="gpt-4",
|
||||
messages=[{"role": "user", "content": "Hello"}],
|
||||
extra_headers={
|
||||
"Helicone-Session-Id": "session-abc-123",
|
||||
"Helicone-Session-Path": "conversation/greeting"
|
||||
}
|
||||
)
|
||||
```python
|
||||
import openai
|
||||
|
||||
# Follow-up request in same session
|
||||
response2 = client.chat.completions.create(
|
||||
model="gpt-4",
|
||||
messages=[{"role": "user", "content": "Tell me more"}],
|
||||
extra_headers={
|
||||
"Helicone-Session-Id": "session-abc-123",
|
||||
"Helicone-Session-Path": "conversation/follow-up"
|
||||
}
|
||||
)
|
||||
```
|
||||
client = openai.OpenAI(
|
||||
api_key="anything",
|
||||
base_url="http://localhost:4000"
|
||||
)
|
||||
|
||||
</TabItem>
|
||||
# First request in session
|
||||
response1 = client.chat.completions.create(
|
||||
model="gpt-4",
|
||||
messages=[{"role": "user", "content": "Hello"}],
|
||||
extra_headers={
|
||||
"Helicone-Session-Id": "session-abc-123",
|
||||
"Helicone-Session-Path": "conversation/greeting"
|
||||
}
|
||||
)
|
||||
|
||||
# Follow-up request in same session
|
||||
response2 = client.chat.completions.create(
|
||||
model="gpt-4",
|
||||
messages=[{"role": "user", "content": "Tell me more"}],
|
||||
extra_headers={
|
||||
"Helicone-Session-Id": "session-abc-123",
|
||||
"Helicone-Session-Path": "conversation/follow-up"
|
||||
}
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
- `Helicone-Session-Id`: Unique identifier for the session to group related requests
|
||||
|
|
@ -304,52 +298,50 @@ response2 = client.chat.completions.create(
|
|||
## Retry and Fallback Mechanisms
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="Python SDK">
|
||||
<TabItem value="sdk" label="Python SDK">
|
||||
|
||||
```python
|
||||
import litellm
|
||||
```python
|
||||
import litellm
|
||||
|
||||
litellm.api_base = "https://oai.hconeai.com/v1"
|
||||
litellm.metadata = {
|
||||
"Helicone-Auth": f"Bearer {os.getenv('HELICONE_API_KEY')}",
|
||||
"Helicone-Retry-Enabled": "true",
|
||||
"helicone-retry-num": "3",
|
||||
"helicone-retry-factor": "2", # Exponential backoff
|
||||
"Helicone-Fallbacks": '["gpt-3.5-turbo", "gpt-4"]',
|
||||
}
|
||||
litellm.api_base = "https://ai-gateway.helicone.ai/"
|
||||
litellm.metadata = {
|
||||
"Helicone-Retry-Enabled": "true",
|
||||
"helicone-retry-num": "3",
|
||||
"helicone-retry-factor": "2",
|
||||
}
|
||||
|
||||
response = litellm.completion(
|
||||
model="gpt-4",
|
||||
messages=[{"role": "user", "content": "Hello"}]
|
||||
)
|
||||
```
|
||||
response = litellm.completion(
|
||||
model="helicone/gpt-4o-mini/openai,claude-3-5-sonnet-20241022/anthropic", # Try OpenAI first, then fallback to Anthropic, then continue with other models
|
||||
messages=[{"role": "user", "content": "Hello"}]
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
```yaml title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
api_base: "https://oai.hconeai.com/v1"
|
||||
```yaml title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
api_base: "https://oai.hconeai.com/v1"
|
||||
|
||||
default_litellm_params:
|
||||
headers:
|
||||
Helicone-Auth: "Bearer ${HELICONE_API_KEY}"
|
||||
Helicone-Retry-Enabled: "true"
|
||||
helicone-retry-num: "3"
|
||||
helicone-retry-factor: "2"
|
||||
Helicone-Fallbacks: '["gpt-3.5-turbo", "gpt-4"]'
|
||||
default_litellm_params:
|
||||
headers:
|
||||
Helicone-Auth: "Bearer ${HELICONE_API_KEY}"
|
||||
Helicone-Retry-Enabled: "true"
|
||||
helicone-retry-num: "3"
|
||||
helicone-retry-factor: "2"
|
||||
Helicone-Fallbacks: '["gpt-3.5-turbo", "gpt-4"]'
|
||||
|
||||
environment_variables:
|
||||
HELICONE_API_KEY: "your-helicone-key"
|
||||
OPENAI_API_KEY: "your-openai-key"
|
||||
```
|
||||
environment_variables:
|
||||
HELICONE_API_KEY: "your-helicone-key"
|
||||
OPENAI_API_KEY: "your-openai-key"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
> **Supported Headers** - For a full list of supported Helicone headers and their descriptions, please refer to the [Helicone documentation](https://docs.helicone.ai/getting-started/quick-start).
|
||||
> **Supported Headers** - For a full list of supported Helicone headers and their descriptions, please refer to the [Helicone documentation](https://docs.helicone.ai/features/advanced-usage/custom-properties).
|
||||
> By utilizing these headers and metadata options, you can gain deeper insights into your LLM usage, optimize performance, and better manage your AI workflows with Helicone and LiteLLM.
|
||||
|
|
|
|||
|
|
@ -8,6 +8,18 @@ OpenTelemetry is a CNCF standard for observability. It connects to any observabi
|
|||
|
||||
<Image img={require('../../img/traceloop_dash.png')} />
|
||||
|
||||
:::note Change in v1.81.0
|
||||
|
||||
From v1.81.0, the request/response will be set as attributes on the parent "Received Proxy Server Request" span by default. This allows you to see the request/response in the parent span in your observability tool.
|
||||
|
||||
To use the older behavior with nested "litellm_request" spans, set the following environment variable:
|
||||
|
||||
```shell
|
||||
USE_OTEL_LITELLM_REQUEST_SPAN=true
|
||||
```
|
||||
|
||||
:::
|
||||
|
||||
## Getting Started
|
||||
|
||||
Install the OpenTelemetry SDK:
|
||||
|
|
|
|||
|
|
@ -6,7 +6,7 @@ Open source tracing and evaluation platform
|
|||
|
||||
:::tip
|
||||
|
||||
This is community maintained, Please make an issue if you run into a bug
|
||||
This is community maintained. Please make an issue if you run into a bug:
|
||||
https://github.com/BerriAI/litellm
|
||||
|
||||
:::
|
||||
|
|
@ -31,17 +31,16 @@ litellm.callbacks = ["arize_phoenix"]
|
|||
import litellm
|
||||
import os
|
||||
|
||||
os.environ["PHOENIX_API_KEY"] = "" # Necessary only using Phoenix Cloud
|
||||
os.environ["PHOENIX_COLLECTOR_HTTP_ENDPOINT"] = "" # The URL of your Phoenix OSS instance e.g. http://localhost:6006/v1/traces
|
||||
# This defaults to https://app.phoenix.arize.com/v1/traces for Phoenix Cloud
|
||||
# Set env variables
|
||||
os.environ["PHOENIX_API_KEY"] = "d0*****" # Set the Phoenix API key here. It is necessary only when using Phoenix Cloud.
|
||||
os.environ["PHOENIX_COLLECTOR_HTTP_ENDPOINT"] = "https://app.phoenix.arize.com/s/<space-name>/v1/traces" # Set the URL of your Phoenix OSS instance, otherwise tracer would use https://app.phoenix.arize.com/v1/traces for Phoenix Cloud.
|
||||
os.environ["PHOENIX_PROJECT_NAME"] = "litellm" # Configure the project name, otherwise traces would go to "default" project.
|
||||
os.environ['OPENAI_API_KEY'] = "fake-key" # Set the OpenAI API key here.
|
||||
|
||||
# LLM API Keys
|
||||
os.environ['OPENAI_API_KEY']=""
|
||||
|
||||
# set arize as a callback, litellm will send the data to arize
|
||||
# Set arize_phoenix as a callback & LiteLLM will send the data to Phoenix.
|
||||
litellm.callbacks = ["arize_phoenix"]
|
||||
|
||||
# openai call
|
||||
|
||||
# OpenAI call
|
||||
response = litellm.completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[
|
||||
|
|
@ -50,8 +49,9 @@ response = litellm.completion(
|
|||
)
|
||||
```
|
||||
|
||||
### Using with LiteLLM Proxy
|
||||
## Using with LiteLLM Proxy
|
||||
|
||||
1. Setup config.yaml
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
|
|
@ -64,12 +64,63 @@ model_list:
|
|||
litellm_settings:
|
||||
callbacks: ["arize_phoenix"]
|
||||
|
||||
general_settings:
|
||||
master_key: "sk-1234"
|
||||
|
||||
environment_variables:
|
||||
PHOENIX_API_KEY: "d0*****"
|
||||
PHOENIX_COLLECTOR_ENDPOINT: "https://app.phoenix.arize.com/v1/traces" # OPTIONAL, for setting the GRPC endpoint
|
||||
PHOENIX_COLLECTOR_HTTP_ENDPOINT: "https://app.phoenix.arize.com/v1/traces" # OPTIONAL, for setting the HTTP endpoint
|
||||
PHOENIX_COLLECTOR_ENDPOINT: "https://app.phoenix.arize.com/s/<space-name>/v1/traces" # OPTIONAL - For setting the gRPC endpoint
|
||||
PHOENIX_COLLECTOR_HTTP_ENDPOINT: "https://app.phoenix.arize.com/s/<space-name>/v1/traces" # OPTIONAL - For setting the HTTP endpoint
|
||||
```
|
||||
|
||||
2. Start the proxy
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
3. Test it!
|
||||
|
||||
```bash
|
||||
curl -X POST 'http://0.0.0.0:4000/chat/completions' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-d '{ "model": "gpt-4o", "messages": [{"role": "user", "content": "Hi 👋 - i'm openai"}]}'
|
||||
```
|
||||
|
||||
## Supported Phoenix Endpoints
|
||||
Phoenix now supports multiple deployment types. The correct endpoint depends on which version of Phoenix Cloud you are using.
|
||||
|
||||
**Phoenix Cloud (With Spaces - New Version)**
|
||||
Use this if your Phoenix URL contains `/s/<space-name>` path.
|
||||
|
||||
```bash
|
||||
https://app.phoenix.arize.com/s/<space-name>/v1/traces
|
||||
```
|
||||
|
||||
**Phoenix Cloud (Legacy - Deprecated)**
|
||||
Use this only if your deployment still shows the `/legacy` pattern.
|
||||
|
||||
```bash
|
||||
https://app.phoenix.arize.com/legacy/v1/traces
|
||||
```
|
||||
|
||||
**Phoenix Cloud (Without Spaces - Old Version)**
|
||||
Use this if your Phoenix Cloud URL does not contain `/s/<space-name>` or `/legacy` path.
|
||||
|
||||
```bash
|
||||
https://app.phoenix.arize.com/v1/traces
|
||||
```
|
||||
|
||||
**Self-Hosted Phoenix (Local Instance)**
|
||||
Use this when running Phoenix on your machine or a private server.
|
||||
|
||||
```bash
|
||||
http://localhost:6006/v1/traces
|
||||
```
|
||||
|
||||
Depending on which Phoenix Cloud version or deployment you are using, you should set the corresponding endpoint in `PHOENIX_COLLECTOR_HTTP_ENDPOINT` or `PHOENIX_COLLECTOR_ENDPOINT`.
|
||||
|
||||
## Support & Talk to Founders
|
||||
|
||||
- [Schedule Demo 👋](https://calendly.com/d/4mp-gd3-k5k/berriai-1-1-onboarding-litellm-hosted-version)
|
||||
|
|
|
|||
287
docs/my-website/docs/observability/sumologic_integration.md
Normal file
287
docs/my-website/docs/observability/sumologic_integration.md
Normal file
|
|
@ -0,0 +1,287 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Sumo Logic
|
||||
|
||||
Send LiteLLM logs to Sumo Logic for observability, monitoring, and analysis.
|
||||
|
||||
Sumo Logic is a cloud-native machine data analytics platform that provides real-time insights into your applications and infrastructure.
|
||||
https://www.sumologic.com/
|
||||
|
||||
:::info
|
||||
We want to learn how we can make the callbacks better! Meet the LiteLLM [founders](https://calendly.com/d/4mp-gd3-k5k/berriai-1-1-onboarding-litellm-hosted-version) or
|
||||
join our [discord](https://discord.gg/wuPM9dRgDw)
|
||||
:::
|
||||
|
||||
## Pre-Requisites
|
||||
|
||||
1. Create a Sumo Logic account at https://www.sumologic.com/
|
||||
2. Set up an HTTP Logs and Metrics Source in Sumo Logic:
|
||||
- Go to **Manage Data** > **Collection** > **Collection**
|
||||
- Click **Add Source** next to a Hosted Collector
|
||||
- Select **HTTP Logs & Metrics**
|
||||
- Copy the generated URL (it contains the authentication token)
|
||||
|
||||
For more details, see the [HTTP Logs & Metrics Source](https://www.sumologic.com/help/docs/send-data/hosted-collectors/http-source/logs-metrics/) documentation.
|
||||
|
||||
```shell
|
||||
pip install litellm
|
||||
```
|
||||
|
||||
## Quick Start
|
||||
|
||||
Use just 2 lines of code to instantly log your LLM responses to Sumo Logic.
|
||||
|
||||
The Sumo Logic HTTP Source URL includes the authentication token, so no separate API key is required.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="python" label="SDK">
|
||||
|
||||
```python
|
||||
litellm.callbacks = ["sumologic"]
|
||||
```
|
||||
|
||||
```python
|
||||
import litellm
|
||||
import os
|
||||
|
||||
# Sumo Logic HTTP Source URL (includes auth token)
|
||||
os.environ["SUMOLOGIC_WEBHOOK_URL"] = "https://collectors.sumologic.com/receiver/v1/http/your-token-here"
|
||||
|
||||
# LLM API Keys
|
||||
os.environ['OPENAI_API_KEY'] = ""
|
||||
|
||||
# Set sumologic as a callback
|
||||
litellm.callbacks = ["sumologic"]
|
||||
|
||||
# OpenAI call
|
||||
response = litellm.completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[
|
||||
{"role": "user", "content": "Hi 👋 - I'm testing Sumo Logic integration"}
|
||||
]
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
1. Setup config.yaml
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-3.5-turbo
|
||||
litellm_params:
|
||||
model: openai/gpt-3.5-turbo
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
litellm_settings:
|
||||
callbacks: ["sumologic"]
|
||||
|
||||
environment_variables:
|
||||
SUMOLOGIC_WEBHOOK_URL: os.environ/SUMOLOGIC_WEBHOOK_URL
|
||||
```
|
||||
|
||||
2. Start LiteLLM Proxy
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
3. Test it!
|
||||
|
||||
```bash
|
||||
curl -L -X POST 'http://0.0.0.0:4000/chat/completions' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-d '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Hey, how are you?"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## What Data is Logged?
|
||||
|
||||
LiteLLM sends the [Standard Logging Payload](https://docs.litellm.ai/docs/proxy/logging_spec) to Sumo Logic, which includes:
|
||||
|
||||
- **Request details**: Model, messages, parameters
|
||||
- **Response details**: Completion text, token usage, latency
|
||||
- **Metadata**: User ID, custom metadata, timestamps
|
||||
- **Cost tracking**: Response cost based on token usage
|
||||
|
||||
Example payload:
|
||||
|
||||
```json
|
||||
{
|
||||
"id": "chatcmpl-123",
|
||||
"call_type": "litellm.completion",
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{"role": "user", "content": "Hello"}
|
||||
],
|
||||
"response": {
|
||||
"choices": [{
|
||||
"message": {
|
||||
"role": "assistant",
|
||||
"content": "Hi there!"
|
||||
}
|
||||
}]
|
||||
},
|
||||
"usage": {
|
||||
"prompt_tokens": 10,
|
||||
"completion_tokens": 5,
|
||||
"total_tokens": 15
|
||||
},
|
||||
"response_cost": 0.0001,
|
||||
"start_time": "2024-01-01T00:00:00",
|
||||
"end_time": "2024-01-01T00:00:01"
|
||||
}
|
||||
```
|
||||
|
||||
## Advanced Configuration
|
||||
|
||||
### Batching Settings
|
||||
|
||||
Control how LiteLLM batches logs before sending to Sumo Logic:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="python" label="SDK">
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
os.environ["SUMOLOGIC_WEBHOOK_URL"] = "https://collectors.sumologic.com/receiver/v1/http/your-token"
|
||||
|
||||
litellm.callbacks = ["sumologic"]
|
||||
|
||||
# Configure batch settings (optional)
|
||||
# These are inherited from CustomBatchLogger
|
||||
# Default batch_size: 100
|
||||
# Default flush_interval: 60 seconds
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
callbacks: ["sumologic"]
|
||||
|
||||
environment_variables:
|
||||
SUMOLOGIC_WEBHOOK_URL: os.environ/SUMOLOGIC_WEBHOOK_URL
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Compressed Data
|
||||
|
||||
Sumo Logic supports compressed data (gzip or deflate). LiteLLM automatically handles compression when beneficial.
|
||||
|
||||
Benefits:
|
||||
- Reduced network usage
|
||||
- Faster message delivery
|
||||
- Lower data transfer costs
|
||||
|
||||
### Query Logs in Sumo Logic
|
||||
|
||||
Once logs are flowing to Sumo Logic, you can query them using the Sumo Logic Query Language:
|
||||
|
||||
```sql
|
||||
_sourceCategory=litellm
|
||||
| json "model", "response_cost", "usage.total_tokens" as model, cost, tokens
|
||||
| sum(cost) by model
|
||||
```
|
||||
|
||||
Example queries:
|
||||
|
||||
**Total cost by model:**
|
||||
```sql
|
||||
_sourceCategory=litellm
|
||||
| json "model", "response_cost" as model, cost
|
||||
| sum(cost) as total_cost by model
|
||||
| sort by total_cost desc
|
||||
```
|
||||
|
||||
**Average response time:**
|
||||
```sql
|
||||
_sourceCategory=litellm
|
||||
| json "start_time", "end_time" as start, end
|
||||
| parse regex field=start "(?<start_ms>\d+)"
|
||||
| parse regex field=end "(?<end_ms>\d+)"
|
||||
| (end_ms - start_ms) as response_time_ms
|
||||
| avg(response_time_ms) as avg_response_time
|
||||
```
|
||||
|
||||
**Requests per user:**
|
||||
```sql
|
||||
_sourceCategory=litellm
|
||||
| json "model_parameters.user" as user
|
||||
| count by user
|
||||
```
|
||||
|
||||
## Authentication
|
||||
|
||||
The Sumo Logic HTTP Source URL includes the authentication token, so you only need to set the `SUMOLOGIC_WEBHOOK_URL` environment variable.
|
||||
|
||||
**Security Best Practices:**
|
||||
- Keep your HTTP Source URL private (it contains the auth token)
|
||||
- Store it in environment variables or secrets management
|
||||
- Regenerate the URL if it's compromised (in Sumo Logic UI)
|
||||
- Use separate HTTP Sources for different environments (dev, staging, prod)
|
||||
|
||||
## Getting Your Sumo Logic URL
|
||||
|
||||
1. Log in to [Sumo Logic](https://www.sumologic.com/)
|
||||
2. Go to **Manage Data** > **Collection** > **Collection**
|
||||
3. Click **Add Source** next to a Hosted Collector
|
||||
4. Select **HTTP Logs & Metrics**
|
||||
5. Configure the source:
|
||||
- **Name**: LiteLLM Logs
|
||||
- **Source Category**: litellm (optional, but helps with queries)
|
||||
6. Click **Save**
|
||||
7. Copy the displayed URL - it will look like:
|
||||
```
|
||||
https://collectors.sumologic.com/receiver/v1/http/ZaVnC4dhaV39Tn37...
|
||||
```
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
### Logs not appearing in Sumo Logic
|
||||
|
||||
1. **Verify the URL**: Make sure `SUMOLOGIC_WEBHOOK_URL` is set correctly
|
||||
2. **Check the HTTP Source**: Ensure it's active in Sumo Logic UI
|
||||
3. **Wait for batching**: Logs are sent in batches, wait 60 seconds
|
||||
4. **Check for errors**: Enable debug logging in LiteLLM:
|
||||
```python
|
||||
litellm.set_verbose = True
|
||||
```
|
||||
|
||||
### URL Format
|
||||
|
||||
The URL must be the complete HTTP Source URL from Sumo Logic:
|
||||
- ✅ Correct: `https://collectors.sumologic.com/receiver/v1/http/ZaVnC4dhaV39Tn37...`
|
||||
|
||||
### No authentication errors
|
||||
|
||||
If you get authentication errors, regenerate the HTTP Source URL in Sumo Logic:
|
||||
1. Go to your HTTP Source in Sumo Logic
|
||||
2. Click the settings icon
|
||||
3. Click **Show URL**
|
||||
4. Click **Regenerate URL**
|
||||
5. Update your `SUMOLOGIC_WEBHOOK_URL` environment variable
|
||||
|
||||
## Support & Talk to Founders
|
||||
|
||||
- [Schedule Demo 👋](https://calendly.com/d/4mp-gd3-k5k/berriai-1-1-onboarding-litellm-hosted-version)
|
||||
- [Community Discord 💭](https://discord.gg/wuPM9dRgDw)
|
||||
- Our numbers 📞 +1 (770) 8783-106 / +1 (412) 618-6238
|
||||
- Our emails ✉️ ishaan@berri.ai / krrish@berri.ai
|
||||
|
|
@ -7,7 +7,7 @@ Pass-through endpoints for Anthropic - call provider-specific endpoint, in nativ
|
|||
|
||||
| Feature | Supported | Notes |
|
||||
|-------|-------|-------|
|
||||
| Cost Tracking | ✅ | supports all models on `/messages` endpoint |
|
||||
| Cost Tracking | ✅ | supports all models on `/messages`, `/v1/messages/batches` endpoint |
|
||||
| Logging | ✅ | works across all integrations |
|
||||
| End-user Tracking | ✅ | disable prometheus tracking via `litellm.disable_end_user_cost_tracking_prometheus_only`|
|
||||
| Streaming | ✅ | |
|
||||
|
|
@ -263,6 +263,19 @@ curl https://api.anthropic.com/v1/messages/batches \
|
|||
}'
|
||||
```
|
||||
|
||||
:::note Configuration Required for Batch Cost Tracking
|
||||
For batch passthrough cost tracking to work properly, you need to define the Anthropic model in your `proxy_config.yaml`:
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-sonnet-4-5-20250929 # or any alias
|
||||
litellm_params:
|
||||
model: anthropic/claude-sonnet-4-5-20250929
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
```
|
||||
|
||||
This ensures the polling mechanism can correctly identify the provider and retrieve batch status for cost calculation.
|
||||
:::
|
||||
|
||||
## Advanced
|
||||
|
||||
|
|
|
|||
10
docs/my-website/docs/projects/Agent Lightning.md
Normal file
10
docs/my-website/docs/projects/Agent Lightning.md
Normal file
|
|
@ -0,0 +1,10 @@
|
|||
|
||||
# Agent Lightning
|
||||
|
||||
[Agent Lightning](https://github.com/microsoft/agent-lightning) is Microsoft's open-source framework for training and optimizing AI agents with Reinforcement Learning, Automatic Prompt Optimization, and Supervised Fine-tuning — with almost zero code changes.
|
||||
|
||||
It works with any agent framework including LangChain, OpenAI Agents SDK, AutoGen, and CrewAI. Agent Lightning uses LiteLLM Proxy under the hood to route LLM requests and collect traces that power its training algorithms.
|
||||
|
||||
- [GitHub](https://github.com/microsoft/agent-lightning)
|
||||
- [Docs](https://microsoft.github.io/agent-lightning/)
|
||||
- [arXiv Paper](https://arxiv.org/abs/2508.03680)
|
||||
21
docs/my-website/docs/projects/Google ADK.md
Normal file
21
docs/my-website/docs/projects/Google ADK.md
Normal file
|
|
@ -0,0 +1,21 @@
|
|||
|
||||
# Google ADK (Agent Development Kit)
|
||||
|
||||
[Google ADK](https://github.com/google/adk-python) is an open-source, code-first Python framework for building, evaluating, and deploying sophisticated AI agents. While optimized for Gemini, ADK is model-agnostic and supports LiteLLM for using 100+ providers.
|
||||
|
||||
```python
|
||||
from google.adk.agents.llm_agent import Agent
|
||||
from google.adk.models.lite_llm import LiteLlm
|
||||
|
||||
root_agent = Agent(
|
||||
model=LiteLlm(model="openai/gpt-4o"), # Or any LiteLLM-supported model
|
||||
name="my_agent",
|
||||
description="An agent using LiteLLM",
|
||||
instruction="You are a helpful assistant.",
|
||||
tools=[your_tools],
|
||||
)
|
||||
```
|
||||
|
||||
- [GitHub](https://github.com/google/adk-python)
|
||||
- [Documentation](https://google.github.io/adk-docs)
|
||||
- [LiteLLM Samples](https://github.com/google/adk-python/tree/main/contributing/samples/hello_world_litellm)
|
||||
8
docs/my-website/docs/projects/GraphRAG.md
Normal file
8
docs/my-website/docs/projects/GraphRAG.md
Normal file
|
|
@ -0,0 +1,8 @@
|
|||
|
||||
# Microsoft GraphRAG
|
||||
|
||||
GraphRAG is a data pipeline and transformation suite that extracts meaningful, structured data from unstructured text using the power of LLMs. It uses a graph-based approach to RAG (Retrieval-Augmented Generation) that leverages knowledge graphs to improve reasoning over private datasets.
|
||||
|
||||
- [Github](https://github.com/microsoft/graphrag)
|
||||
- [Docs](https://microsoft.github.io/graphrag/)
|
||||
- [Paper](https://arxiv.org/pdf/2404.16130)
|
||||
24
docs/my-website/docs/projects/Harbor.md
Normal file
24
docs/my-website/docs/projects/Harbor.md
Normal file
|
|
@ -0,0 +1,24 @@
|
|||
|
||||
# Harbor
|
||||
|
||||
[Harbor](https://github.com/laude-institute/harbor) is a framework from the creators of Terminal-Bench for evaluating and optimizing agents and language models. It uses LiteLLM to call 100+ LLM providers.
|
||||
|
||||
```bash
|
||||
# Install
|
||||
pip install harbor
|
||||
|
||||
# Run a benchmark with any LiteLLM-supported model
|
||||
harbor run --dataset terminal-bench@2.0 \
|
||||
--agent claude-code \
|
||||
--model anthropic/claude-opus-4-1 \
|
||||
--n-concurrent 4
|
||||
```
|
||||
|
||||
Key features:
|
||||
- Evaluate agents like Claude Code, OpenHands, Codex CLI
|
||||
- Build and share benchmarks and environments
|
||||
- Run experiments in parallel across cloud providers (Daytona, Modal)
|
||||
- Generate rollouts for RL optimization
|
||||
|
||||
- [GitHub](https://github.com/laude-institute/harbor)
|
||||
- [Documentation](https://harborframework.com/docs)
|
||||
17
docs/my-website/docs/projects/mini-swe-agent.md
Normal file
17
docs/my-website/docs/projects/mini-swe-agent.md
Normal file
|
|
@ -0,0 +1,17 @@
|
|||
# mini-swe-agent
|
||||
|
||||
**mini-swe-agent** The 100 line AI agent that solves GitHub issues & more.
|
||||
|
||||
Key features:
|
||||
- Just 100 lines of Python - radically simple and hackable
|
||||
- Uses bash only (no custom tools) for maximum flexibility
|
||||
- Built on LiteLLM for model flexibility
|
||||
- Comes with CLI and Python bindings
|
||||
- Deployable anywhere: local, docker, podman, apptainer
|
||||
|
||||
Perfect for researchers, developers who want readable tools, and engineers who need easy deployment.
|
||||
|
||||
- [Website](https://mini-swe-agent.com/latest/)
|
||||
- [GitHub](https://github.com/SWE-agent/mini-swe-agent)
|
||||
- [Quick Start](https://mini-swe-agent.com/latest/quickstart/)
|
||||
- [Documentation](https://mini-swe-agent.com/latest/)
|
||||
22
docs/my-website/docs/projects/openai-agents.md
Normal file
22
docs/my-website/docs/projects/openai-agents.md
Normal file
|
|
@ -0,0 +1,22 @@
|
|||
|
||||
# OpenAI Agents SDK
|
||||
|
||||
The [OpenAI Agents SDK](https://github.com/openai/openai-agents-python) is a lightweight framework for building multi-agent workflows.
|
||||
It includes an official LiteLLM extension that lets you use any of the 100+ supported providers (Anthropic, Gemini, Mistral, Bedrock, etc.)
|
||||
|
||||
```python
|
||||
from agents import Agent, Runner
|
||||
from agents.extensions.models.litellm_model import LitellmModel
|
||||
|
||||
agent = Agent(
|
||||
name="Assistant",
|
||||
instructions="You are a helpful assistant.",
|
||||
model=LitellmModel(model="provider/model-name")
|
||||
)
|
||||
|
||||
result = Runner.run_sync(agent, "your_prompt_here")
|
||||
print("Result:", result.final_output)
|
||||
```
|
||||
|
||||
- [GitHub](https://github.com/openai/openai-agents-python)
|
||||
- [LiteLLM Extension Docs](https://openai.github.io/openai-agents-python/ref/extensions/litellm/)
|
||||
124
docs/my-website/docs/provider_registration/add_model_pricing.md
Normal file
124
docs/my-website/docs/provider_registration/add_model_pricing.md
Normal file
|
|
@ -0,0 +1,124 @@
|
|||
---
|
||||
title: "Add Model Pricing & Context Window"
|
||||
---
|
||||
|
||||
To add pricing or context window information for a model, simply make a PR to this file:
|
||||
|
||||
**[model_prices_and_context_window.json](https://github.com/BerriAI/litellm/blob/main/model_prices_and_context_window.json)**
|
||||
|
||||
### Sample Spec
|
||||
|
||||
Here's the full specification with all available fields:
|
||||
|
||||
```json
|
||||
{
|
||||
"sample_spec": {
|
||||
"code_interpreter_cost_per_session": 0.0,
|
||||
"computer_use_input_cost_per_1k_tokens": 0.0,
|
||||
"computer_use_output_cost_per_1k_tokens": 0.0,
|
||||
"deprecation_date": "date when the model becomes deprecated in the format YYYY-MM-DD",
|
||||
"file_search_cost_per_1k_calls": 0.0,
|
||||
"file_search_cost_per_gb_per_day": 0.0,
|
||||
"input_cost_per_audio_token": 0.0,
|
||||
"input_cost_per_token": 0.0,
|
||||
"litellm_provider": "one of https://docs.litellm.ai/docs/providers",
|
||||
"max_input_tokens": "max input tokens, if the provider specifies it. if not default to max_tokens",
|
||||
"max_output_tokens": "max output tokens, if the provider specifies it. if not default to max_tokens",
|
||||
"max_tokens": "LEGACY parameter. set to max_output_tokens if provider specifies it. IF not set to max_input_tokens, if provider specifies it.",
|
||||
"mode": "one of: chat, embedding, completion, image_generation, audio_transcription, audio_speech, image_generation, moderation, rerank, search",
|
||||
"output_cost_per_reasoning_token": 0.0,
|
||||
"output_cost_per_token": 0.0,
|
||||
"search_context_cost_per_query": {
|
||||
"search_context_size_high": 0.0,
|
||||
"search_context_size_low": 0.0,
|
||||
"search_context_size_medium": 0.0
|
||||
},
|
||||
"supported_regions": [
|
||||
"global",
|
||||
"us-west-2",
|
||||
"eu-west-1",
|
||||
"ap-southeast-1",
|
||||
"ap-northeast-1"
|
||||
],
|
||||
"supports_audio_input": true,
|
||||
"supports_audio_output": true,
|
||||
"supports_function_calling": true,
|
||||
"supports_parallel_function_calling": true,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_response_schema": true,
|
||||
"supports_system_messages": true,
|
||||
"supports_vision": true,
|
||||
"supports_web_search": true,
|
||||
"vector_store_cost_per_gb_per_day": 0.0
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Examples
|
||||
|
||||
#### Anthropic Claude
|
||||
|
||||
```json
|
||||
{
|
||||
"claude-3-5-haiku-20241022": {
|
||||
"cache_creation_input_token_cost": 1e-06,
|
||||
"cache_creation_input_token_cost_above_1hr": 6e-06,
|
||||
"cache_read_input_token_cost": 8e-08,
|
||||
"deprecation_date": "2025-10-01",
|
||||
"input_cost_per_token": 8e-07,
|
||||
"litellm_provider": "anthropic",
|
||||
"max_input_tokens": 200000,
|
||||
"max_output_tokens": 8192,
|
||||
"max_tokens": 8192,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 4e-06,
|
||||
"search_context_cost_per_query": {
|
||||
"search_context_size_high": 0.01,
|
||||
"search_context_size_low": 0.01,
|
||||
"search_context_size_medium": 0.01
|
||||
},
|
||||
"supports_assistant_prefill": true,
|
||||
"supports_function_calling": true,
|
||||
"supports_pdf_input": true,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_vision": true
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
#### Vertex AI Gemini
|
||||
|
||||
```json
|
||||
{
|
||||
"vertex_ai/gemini-3-pro-preview": {
|
||||
"cache_read_input_token_cost": 2e-07,
|
||||
"cache_read_input_token_cost_above_200k_tokens": 4e-07,
|
||||
"cache_creation_input_token_cost_above_200k_tokens": 2.5e-07,
|
||||
"input_cost_per_token": 2e-06,
|
||||
"input_cost_per_token_above_200k_tokens": 4e-06,
|
||||
"input_cost_per_token_batches": 1e-06,
|
||||
"litellm_provider": "vertex_ai",
|
||||
"max_audio_length_hours": 8.4,
|
||||
"max_audio_per_prompt": 1,
|
||||
"max_images_per_prompt": 3000,
|
||||
"max_input_tokens": 1048576,
|
||||
"max_output_tokens": 65535,
|
||||
"max_pdf_size_mb": 30,
|
||||
"max_tokens": 65535,
|
||||
"max_video_length": 1,
|
||||
"max_videos_per_prompt": 10,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 1.2e-05,
|
||||
"output_cost_per_token_above_200k_tokens": 1.8e-05,
|
||||
"output_cost_per_token_batches": 6e-06,
|
||||
"supports_function_calling": true,
|
||||
"supports_parallel_function_calling": true,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_system_messages": true,
|
||||
"supports_vision": true
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
That's it! Your PR will be reviewed and merged.
|
||||
|
|
@ -2,6 +2,12 @@
|
|||
title: "Integrate as a Model Provider"
|
||||
---
|
||||
|
||||
## Quick Start for OpenAI-Compatible Providers
|
||||
|
||||
If your API is OpenAI-compatible, you can add support by editing a single JSON file. See [Adding OpenAI-Compatible Providers](/docs/contributing/adding_openai_compatible_providers) for the simple approach.
|
||||
|
||||
---
|
||||
|
||||
This guide focuses on how to setup the classes and configuration necessary to act as a chat provider.
|
||||
|
||||
Please see this guide first and look at the existing code in the codebase to understand how to act as a different provider, e.g. handling embeddings or image-generation.
|
||||
|
|
|
|||
291
docs/my-website/docs/providers/amazon_nova.md
Normal file
291
docs/my-website/docs/providers/amazon_nova.md
Normal file
|
|
@ -0,0 +1,291 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Amazon Nova
|
||||
|
||||
| Property | Details |
|
||||
|-------|-------|
|
||||
| Description | Amazon Nova is a family of foundation models built by Amazon that deliver frontier intelligence and industry-leading price performance. |
|
||||
| Provider Route on LiteLLM | `amazon_nova/` |
|
||||
| Provider Doc | [Amazon Nova ↗](https://docs.aws.amazon.com/nova/latest/userguide/what-is-nova.html) |
|
||||
| Supported OpenAI Endpoints | `/chat/completions`, `v1/responses` |
|
||||
| Other Supported Endpoints | `v1/messages`, `/generateContent` |
|
||||
|
||||
## Authentication
|
||||
|
||||
Amazon Nova uses API key authentication. You can obtain your API key from the [Amazon Nova developer console ↗](https://nova.amazon.com/dev/documentation).
|
||||
|
||||
```bash
|
||||
export AMAZON_NOVA_API_KEY="your-api-key"
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
import os
|
||||
from litellm import completion
|
||||
|
||||
# Set your API key
|
||||
os.environ["AMAZON_NOVA_API_KEY"] = "your-api-key"
|
||||
|
||||
response = completion(
|
||||
model="amazon_nova/nova-micro-v1",
|
||||
messages=[
|
||||
{"role": "system", "content": "You are a helpful assistant"},
|
||||
{"role": "user", "content": "Hello, how are you?"}
|
||||
]
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
### 1. Setup config.yaml
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: amazon-nova-micro
|
||||
litellm_params:
|
||||
model: amazon_nova/nova-micro-v1
|
||||
api_key: os.environ/AMAZON_NOVA_API_KEY
|
||||
```
|
||||
### 2. Start the proxy
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
### 3. Test it
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "amazon-nova-micro",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Hello, how are you?"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Supported Models
|
||||
|
||||
| Model Name | Usage | Context Window |
|
||||
|------------|-------|----------------|
|
||||
| Nova Micro | `completion(model="amazon_nova/nova-micro-v1", messages=messages)` | 128K tokens |
|
||||
| Nova Lite | `completion(model="amazon_nova/nova-lite-v1", messages=messages)` | 300K tokens |
|
||||
| Nova Pro | `completion(model="amazon_nova/nova-pro-v1", messages=messages)` | 300K tokens |
|
||||
| Nova Premier | `completion(model="amazon_nova/nova-premier-v1", messages=messages)` | 1M tokens |
|
||||
|
||||
## Usage - Streaming
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
import os
|
||||
from litellm import completion
|
||||
|
||||
os.environ["AMAZON_NOVA_API_KEY"] = "your-api-key"
|
||||
|
||||
response = completion(
|
||||
model="amazon_nova/nova-micro-v1",
|
||||
messages=[
|
||||
{"role": "system", "content": "You are a helpful assistant"},
|
||||
{"role": "user", "content": "Tell me about machine learning"}
|
||||
],
|
||||
stream=True
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
print(chunk.choices[0].delta.content or "", end="")
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "amazon-nova-micro",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Tell me about machine learning"
|
||||
}
|
||||
],
|
||||
"stream": true
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Function Calling / Tool Usage
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
import os
|
||||
from litellm import completion
|
||||
|
||||
os.environ["AMAZON_NOVA_API_KEY"] = "your-api-key"
|
||||
|
||||
tools = [
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "getCurrentWeather",
|
||||
"description": "Get the current weather in a given city",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {
|
||||
"type": "string",
|
||||
"description": "City and country e.g. San Francisco, CA"
|
||||
}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
|
||||
response = completion(
|
||||
model="amazon_nova/nova-micro-v1",
|
||||
messages=[
|
||||
{"role": "user", "content": "What's the weather like in San Francisco?"}
|
||||
],
|
||||
tools=tools
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "amazon-nova-micro",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What'\''s the weather like in San Francisco?"
|
||||
}
|
||||
],
|
||||
"tools": [
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "getCurrentWeather",
|
||||
"description": "Get the current weather in a given city",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {
|
||||
"type": "string",
|
||||
"description": "City and country e.g. San Francisco, CA"
|
||||
}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Set temperature, top_p, etc.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
import os
|
||||
from litellm import completion
|
||||
|
||||
os.environ["AMAZON_NOVA_API_KEY"] = "your-api-key"
|
||||
|
||||
response = completion(
|
||||
model="amazon_nova/nova-pro-v1",
|
||||
messages=[
|
||||
{"role": "user", "content": "Write a creative story"}
|
||||
],
|
||||
temperature=0.8,
|
||||
max_tokens=500,
|
||||
top_p=0.9
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
**Set on yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: amazon-nova-pro
|
||||
litellm_params:
|
||||
model: amazon_nova/nova-pro-v1
|
||||
temperature: 0.8
|
||||
max_tokens: 500
|
||||
top_p: 0.9
|
||||
```
|
||||
**Set on request**
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "amazon-nova-pro",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Write a creative story"
|
||||
}
|
||||
],
|
||||
"temperature": 0.8,
|
||||
"max_tokens": 500,
|
||||
"top_p": 0.9
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Model Comparison
|
||||
|
||||
| Model | Best For | Speed | Cost | Context |
|
||||
|-------|----------|-------|------|---------|
|
||||
| **Nova Micro** | Simple tasks, high throughput | Fastest | Lowest | 128K |
|
||||
| **Nova Lite** | Balanced performance | Fast | Low | 300K |
|
||||
| **Nova Pro** | Complex reasoning | Medium | Medium | 300K |
|
||||
| **Nova Premier** | Most advanced tasks | Slower | Higher | 1M |
|
||||
|
||||
## Error Handling
|
||||
|
||||
Common error codes and their meanings:
|
||||
|
||||
- `401 Unauthorized`: Invalid API key
|
||||
- `429 Too Many Requests`: Rate limit exceeded
|
||||
- `400 Bad Request`: Invalid request format
|
||||
- `500 Internal Server Error`: Service temporarily unavailable
|
||||
|
|
@ -5,6 +5,7 @@ import TabItem from '@theme/TabItem';
|
|||
LiteLLM supports all anthropic models.
|
||||
|
||||
- `claude-sonnet-4-5-20250929`
|
||||
- `claude-opus-4-5-20251101`
|
||||
- `claude-opus-4-1-20250805`
|
||||
- `claude-4` (`claude-opus-4-20250514`, `claude-sonnet-4-20250514`)
|
||||
- `claude-3.7` (`claude-3-7-sonnet-20250219`)
|
||||
|
|
@ -17,11 +18,11 @@ LiteLLM supports all anthropic models.
|
|||
|
||||
| Property | Details |
|
||||
|-------|-------|
|
||||
| Description | Claude is a highly performant, trustworthy, and intelligent AI platform built by Anthropic. Claude excels at tasks involving language, reasoning, analysis, coding, and more. |
|
||||
| Provider Route on LiteLLM | `anthropic/` (add this prefix to the model name, to route any requests to Anthropic - e.g. `anthropic/claude-3-5-sonnet-20240620`) |
|
||||
| Provider Doc | [Anthropic ↗](https://docs.anthropic.com/en/docs/build-with-claude/overview) |
|
||||
| API Endpoint for Provider | https://api.anthropic.com |
|
||||
| Supported Endpoints | `/chat/completions` |
|
||||
| Description | Claude is a highly performant, trustworthy, and intelligent AI platform built by Anthropic. Claude excels at tasks involving language, reasoning, analysis, coding, and more. Also available via Azure Foundry. |
|
||||
| Provider Route on LiteLLM | `anthropic/` (add this prefix to the model name, to route any requests to Anthropic - e.g. `anthropic/claude-3-5-sonnet-20240620`). For Azure Foundry deployments, use `azure/claude-*` (see [Azure Anthropic documentation](../providers/azure/azure_anthropic)) |
|
||||
| Provider Doc | [Anthropic ↗](https://docs.anthropic.com/en/docs/build-with-claude/overview), [Azure Foundry Claude ↗](https://learn.microsoft.com/en-us/azure/ai-services/foundry-models/claude) |
|
||||
| API Endpoint for Provider | https://api.anthropic.com (or Azure Foundry endpoint: `https://<resource-name>.services.ai.azure.com/anthropic`) |
|
||||
| Supported Endpoints | `/chat/completions`, `/v1/messages` (passthrough) |
|
||||
|
||||
|
||||
## Supported OpenAI Parameters
|
||||
|
|
@ -40,15 +41,120 @@ Check this in code, [here](../completion/input.md#translated-openai-params)
|
|||
"extra_headers",
|
||||
"parallel_tool_calls",
|
||||
"response_format",
|
||||
"user"
|
||||
"user",
|
||||
"reasoning_effort",
|
||||
```
|
||||
|
||||
:::info
|
||||
|
||||
Anthropic API fails requests when `max_tokens` are not passed. Due to this litellm passes `max_tokens=4096` when no `max_tokens` are passed.
|
||||
**Notes:**
|
||||
- Anthropic API fails requests when `max_tokens` are not passed. Due to this litellm passes `max_tokens=4096` when no `max_tokens` are passed.
|
||||
- `response_format` is fully supported for Claude Sonnet 4.5 and Opus 4.1 models (see [Structured Outputs](#structured-outputs) section)
|
||||
- `reasoning_effort` is automatically mapped to `output_config={"effort": ...}` for Claude Opus 4.5 models (see [Effort Parameter](./anthropic_effort.md))
|
||||
|
||||
:::
|
||||
|
||||
## **Structured Outputs**
|
||||
|
||||
LiteLLM supports Anthropic's [structured outputs feature](https://platform.claude.com/docs/en/build-with-claude/structured-outputs) for Claude Sonnet 4.5 and Opus 4.1 models. When you use `response_format` with these models, LiteLLM automatically:
|
||||
- Adds the required `structured-outputs-2025-11-13` beta header
|
||||
- Transforms OpenAI's `response_format` to Anthropic's `output_format` format
|
||||
|
||||
### Supported Models
|
||||
- `sonnet-4-5` or `sonnet-4.5` (all Sonnet 4.5 variants)
|
||||
- `opus-4-1` or `opus-4.1` (all Opus 4.1 variants)
|
||||
- `opus-4-5` or `opus-4.5` (all Opus 4.5 variants)
|
||||
|
||||
### Example Usage
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="LiteLLM SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="claude-sonnet-4-5-20250929",
|
||||
messages=[{"role": "user", "content": "What is the capital of France?"}],
|
||||
response_format={
|
||||
"type": "json_schema",
|
||||
"json_schema": {
|
||||
"name": "capital_response",
|
||||
"strict": True,
|
||||
"schema": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"country": {"type": "string"},
|
||||
"capital": {"type": "string"}
|
||||
},
|
||||
"required": ["country", "capital"],
|
||||
"additionalProperties": False
|
||||
}
|
||||
}
|
||||
}
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
# Output: {"country": "France", "capital": "Paris"}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
1. Setup config.yaml
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-sonnet-4-5
|
||||
litellm_params:
|
||||
model: anthropic/claude-sonnet-4-5-20250929
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
```
|
||||
|
||||
2. Start proxy
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
3. Test it!
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer $LITELLM_KEY" \
|
||||
-d '{
|
||||
"model": "claude-sonnet-4-5",
|
||||
"messages": [{"role": "user", "content": "What is the capital of France?"}],
|
||||
"response_format": {
|
||||
"type": "json_schema",
|
||||
"json_schema": {
|
||||
"name": "capital_response",
|
||||
"strict": true,
|
||||
"schema": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"country": {"type": "string"},
|
||||
"capital": {"type": "string"}
|
||||
},
|
||||
"required": ["country", "capital"],
|
||||
"additionalProperties": false
|
||||
}
|
||||
}
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
:::info
|
||||
When using structured outputs with supported models, LiteLLM automatically:
|
||||
- Converts OpenAI's `response_format` to Anthropic's `output_schema`
|
||||
- Adds the `anthropic-beta: structured-outputs-2025-11-13` header
|
||||
- Creates a tool with the schema and forces the model to use it
|
||||
:::
|
||||
|
||||
## API Keys
|
||||
|
||||
```python
|
||||
|
|
@ -59,6 +165,22 @@ os.environ["ANTHROPIC_API_KEY"] = "your-api-key"
|
|||
# os.environ["LITELLM_ANTHROPIC_DISABLE_URL_SUFFIX"] = "true" # [OPTIONAL] Disable automatic URL suffix appending
|
||||
```
|
||||
|
||||
:::tip Azure Foundry Support
|
||||
|
||||
Claude models are also available via Microsoft Azure Foundry. Use the `azure/` prefix instead of `anthropic/` and configure Azure authentication. See the [Azure Anthropic documentation](../providers/azure/azure_anthropic) for details.
|
||||
|
||||
Example:
|
||||
```python
|
||||
response = completion(
|
||||
model="azure/claude-sonnet-4-5",
|
||||
api_base="https://<resource-name>.services.ai.azure.com/anthropic",
|
||||
api_key="your-azure-api-key",
|
||||
messages=[{"role": "user", "content": "Hello!"}]
|
||||
)
|
||||
```
|
||||
|
||||
:::
|
||||
|
||||
### Custom API Base
|
||||
|
||||
When using a custom API base for Anthropic (e.g., a proxy or custom endpoint), LiteLLM automatically appends the appropriate suffix (`/v1/messages` or `/v1/complete`) to your base URL.
|
||||
|
|
@ -79,6 +201,30 @@ Without `LITELLM_ANTHROPIC_DISABLE_URL_SUFFIX`:
|
|||
With `LITELLM_ANTHROPIC_DISABLE_URL_SUFFIX=true`:
|
||||
- Base URL `https://my-proxy.com/custom/path` → `https://my-proxy.com/custom/path` (unchanged)
|
||||
|
||||
### Azure AI Foundry (Alternative Method)
|
||||
|
||||
:::tip Recommended Method
|
||||
For full Azure support including Azure AD authentication, use the dedicated [Azure Anthropic provider](./azure/azure_anthropic) with `azure_ai/` prefix.
|
||||
:::
|
||||
|
||||
As an alternative, you can use the `anthropic/` provider directly with your Azure endpoint since Azure exposes Claude using Anthropic's native API.
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="anthropic/claude-sonnet-4-5",
|
||||
api_base="https://<your-resource>.services.ai.azure.com/anthropic",
|
||||
api_key="<your-azure-api-key>",
|
||||
messages=[{"role": "user", "content": "Hello!"}],
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
:::info
|
||||
**Finding your Azure endpoint:** Go to Azure AI Foundry → Your deployment → Overview. Your base URL will be `https://<resource-name>.services.ai.azure.com/anthropic`
|
||||
:::
|
||||
|
||||
## Usage
|
||||
|
||||
```python
|
||||
|
|
@ -953,6 +1099,30 @@ except Exception as e:
|
|||
|
||||
s/o @[Shekhar Patnaik](https://www.linkedin.com/in/patnaikshekhar) for requesting this!
|
||||
|
||||
### Context Management (Beta)
|
||||
|
||||
Anthropic’s [context editing](https://docs.claude.com/en/docs/build-with-claude/context-editing) API lets you automatically clear older tool results or thinking blocks. LiteLLM now forwards the native `context_management` payload when you call Anthropic models, and automatically attaches the required `context-management-2025-06-27` beta header.
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="anthropic/claude-sonnet-4-20250514",
|
||||
messages=[{"role": "user", "content": "Summarize the latest tool results"}],
|
||||
context_management={
|
||||
"edits": [
|
||||
{
|
||||
"type": "clear_tool_uses_20250919",
|
||||
"trigger": {"type": "input_tokens", "value": 30000},
|
||||
"keep": {"type": "tool_uses", "value": 3},
|
||||
"clear_at_least": {"type": "input_tokens", "value": 5000},
|
||||
"exclude_tools": ["web_search"],
|
||||
}
|
||||
]
|
||||
},
|
||||
)
|
||||
```
|
||||
|
||||
### Anthropic Hosted Tools (Computer, Text Editor, Web Search, Memory)
|
||||
|
||||
|
||||
|
|
|
|||
286
docs/my-website/docs/providers/anthropic_effort.md
Normal file
286
docs/my-website/docs/providers/anthropic_effort.md
Normal file
|
|
@ -0,0 +1,286 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Anthropic Effort Parameter
|
||||
|
||||
Control how many tokens Claude uses when responding with the `effort` parameter, trading off between response thoroughness and token efficiency.
|
||||
|
||||
## Overview
|
||||
|
||||
The `effort` parameter allows you to control how eager Claude is about spending tokens when responding to requests. This gives you the ability to trade off between response thoroughness and token efficiency, all with a single model.
|
||||
|
||||
**Note**: The effort parameter is currently in beta and only supported by Claude Opus 4.5. LiteLLM automatically adds the `effort-2025-11-24` beta header when:
|
||||
- `reasoning_effort` parameter is provided (for Claude Opus 4.5 only)
|
||||
|
||||
For Claude Opus 4.5, `reasoning_effort="medium"`—both are automatically mapped to the correct format.
|
||||
|
||||
## How Effort Works
|
||||
|
||||
By default, Claude uses maximum effort—spending as many tokens as needed for the best possible outcome. By lowering the effort level, you can instruct Claude to be more conservative with token usage, optimizing for speed and cost while accepting some reduction in capability.
|
||||
|
||||
**Tip**: Setting `effort` to `"high"` produces exactly the same behavior as omitting the `effort` parameter entirely.
|
||||
|
||||
The effort parameter affects **all tokens** in the response, including:
|
||||
- Text responses and explanations
|
||||
- Tool calls and function arguments
|
||||
- Extended thinking (when enabled)
|
||||
|
||||
This approach has two major advantages:
|
||||
1. It doesn't require thinking to be enabled in order to use it.
|
||||
2. It can affect all token spend including tool calls. For example, lower effort would mean Claude makes fewer tool calls.
|
||||
|
||||
This gives a much greater degree of control over efficiency.
|
||||
|
||||
## Effort Levels
|
||||
|
||||
| Level | Description | Typical use case |
|
||||
|-------|-------------|------------------|
|
||||
| `high` | Maximum capability—Claude uses as many tokens as needed for the best possible outcome. Equivalent to not setting the parameter. | Complex reasoning, difficult coding problems, agentic tasks |
|
||||
| `medium` | Balanced approach with moderate token savings. | Agentic tasks that require a balance of speed, cost, and performance |
|
||||
| `low` | Most efficient—significant token savings with some capability reduction. | Simpler tasks that need the best speed and lowest costs, such as subagents |
|
||||
|
||||
## Quick Start
|
||||
|
||||
### Using LiteLLM SDK
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="python" label="Python">
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-opus-4-5-20251101",
|
||||
messages=[{
|
||||
"role": "user",
|
||||
"content": "Analyze the trade-offs between microservices and monolithic architectures"
|
||||
}],
|
||||
reasoning_effort="medium" # Automatically mapped to output_config for Opus 4.5
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="typescript" label="TypeScript">
|
||||
|
||||
```typescript
|
||||
import Anthropic from "@anthropic-ai/sdk";
|
||||
|
||||
const client = new Anthropic({
|
||||
apiKey: process.env.ANTHROPIC_API_KEY,
|
||||
});
|
||||
|
||||
const response = await client.messages.create({
|
||||
model: "claude-opus-4-5-20251101",
|
||||
max_tokens: 4096,
|
||||
messages: [{
|
||||
role: "user",
|
||||
content: "Analyze the trade-offs between microservices and monolithic architectures"
|
||||
}],
|
||||
output_config: {
|
||||
effort: "medium"
|
||||
}
|
||||
});
|
||||
|
||||
console.log(response.content[0].text);
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Using LiteLLM Proxy
|
||||
|
||||
```bash
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer $LITELLM_API_KEY" \
|
||||
-d '{
|
||||
"model": "anthropic/claude-opus-4-5-20251101",
|
||||
"messages": [{
|
||||
"role": "user",
|
||||
"content": "Analyze the trade-offs between microservices and monolithic architectures"
|
||||
}],
|
||||
"output_config": {
|
||||
"effort": "medium"
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
### Direct Anthropic API Call
|
||||
|
||||
```bash
|
||||
curl https://api.anthropic.com/v1/messages \
|
||||
--header "x-api-key: $ANTHROPIC_API_KEY" \
|
||||
--header "anthropic-version: 2023-06-01" \
|
||||
--header "anthropic-beta: effort-2025-11-24" \
|
||||
--header "content-type: application/json" \
|
||||
--data '{
|
||||
"model": "claude-opus-4-5-20251101",
|
||||
"max_tokens": 4096,
|
||||
"messages": [{
|
||||
"role": "user",
|
||||
"content": "Analyze the trade-offs between microservices and monolithic architectures"
|
||||
}],
|
||||
"output_config": {
|
||||
"effort": "medium"
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
## Model Compatibility
|
||||
|
||||
The effort parameter is currently only supported by:
|
||||
- **Claude Opus 4.5** (`claude-opus-4-5-20251101`)
|
||||
|
||||
## When Should I Adjust the Effort Parameter?
|
||||
|
||||
- Use **high effort** (the default) when you need Claude's best work—complex reasoning, nuanced analysis, difficult coding problems, or any task where quality is the top priority.
|
||||
|
||||
- Use **medium effort** as a balanced option when you want solid performance without the full token expenditure of high effort.
|
||||
|
||||
- Use **low effort** when you're optimizing for speed (because Claude answers with fewer tokens) or cost—for example, simple classification tasks, quick lookups, or high-volume use cases where marginal quality improvements don't justify additional latency or spend.
|
||||
|
||||
## Effort with Tool Use
|
||||
|
||||
When using tools, the effort parameter affects both the explanations around tool calls and the tool calls themselves. Lower effort levels tend to:
|
||||
- Combine multiple operations into fewer tool calls
|
||||
- Make fewer tool calls
|
||||
- Proceed directly to action
|
||||
|
||||
Example with tools:
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-opus-4-5-20251101",
|
||||
messages=[{
|
||||
"role": "user",
|
||||
"content": "Check the weather in multiple cities"
|
||||
}],
|
||||
tools=[{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get weather for a location",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {"type": "string"}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
}
|
||||
}],
|
||||
output_config={
|
||||
"effort": "low" # Will make fewer tool calls
|
||||
}
|
||||
)
|
||||
```
|
||||
|
||||
## Effort with Extended Thinking
|
||||
|
||||
The effort parameter works seamlessly with extended thinking. When both are enabled, effort controls the token budget across all response types:
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-opus-4-5-20251101",
|
||||
messages=[{
|
||||
"role": "user",
|
||||
"content": "Solve this complex problem"
|
||||
}],
|
||||
thinking={
|
||||
"type": "enabled",
|
||||
"budget_tokens": 5000
|
||||
},
|
||||
output_config={
|
||||
"effort": "medium" # Affects both thinking and response tokens
|
||||
}
|
||||
)
|
||||
```
|
||||
|
||||
## Best Practices
|
||||
|
||||
1. **Start with the default (high)** for new tasks, then experiment with lower effort levels if you're looking to optimize costs.
|
||||
|
||||
2. **Use medium effort for production agentic workflows** where you need a balance of quality and efficiency.
|
||||
|
||||
3. **Reserve low effort for high-volume, simple tasks** like classification, routing, or data extraction where speed matters more than nuanced responses.
|
||||
|
||||
4. **Monitor token usage** to understand the actual savings from different effort levels for your specific use cases.
|
||||
|
||||
5. **Test with your specific prompts** as the impact of effort levels can vary based on task complexity.
|
||||
|
||||
## Provider Support
|
||||
|
||||
The effort parameter is supported across all Anthropic-compatible providers:
|
||||
|
||||
- **Standard Anthropic API**: ✅ Supported (Claude Opus 4.5)
|
||||
- **Azure Anthropic / Microsoft Foundry**: ✅ Supported (Claude Opus 4.5)
|
||||
- **Amazon Bedrock**: ✅ Supported (Claude Opus 4.5)
|
||||
- **Google Cloud Vertex AI**: ✅ Supported (Claude Opus 4.5)
|
||||
|
||||
LiteLLM automatically handles:
|
||||
- Beta header injection (`effort-2025-11-24`) for all providers
|
||||
- Parameter mapping: `reasoning_effort` → `output_config={"effort": ...}` for Claude Opus 4.5
|
||||
|
||||
## Usage and Pricing
|
||||
|
||||
Token usage with different effort levels is tracked in the standard usage object. Lower effort levels result in fewer output tokens, which directly reduces costs:
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-opus-4-5-20251101",
|
||||
messages=[{"role": "user", "content": "Analyze this"}],
|
||||
output_config={"effort": "low"}
|
||||
)
|
||||
|
||||
print(f"Output tokens: {response.usage.completion_tokens}")
|
||||
print(f"Total tokens: {response.usage.total_tokens}")
|
||||
```
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
### Beta header not being added
|
||||
|
||||
LiteLLM automatically adds the `effort-2025-11-24` beta header when:
|
||||
- `reasoning_effort` parameter is provided (for Claude Opus 4.5 only)
|
||||
|
||||
If you're not seeing the header:
|
||||
|
||||
1. Ensure you're using `reasoning_effort` parameter
|
||||
2. Verify the model is Claude Opus 4.5
|
||||
3. Check that LiteLLM version supports this feature
|
||||
|
||||
### Invalid effort value error
|
||||
|
||||
Only three values are accepted: `"high"`, `"medium"`, `"low"`. Any other value will raise a validation error:
|
||||
|
||||
```python
|
||||
# ❌ This will raise an error
|
||||
output_config={"effort": "very_low"}
|
||||
|
||||
# ✅ Use one of the valid values
|
||||
output_config={"effort": "low"}
|
||||
```
|
||||
|
||||
### Model not supported
|
||||
|
||||
Currently, only Claude Opus 4.5 supports the effort parameter. Using it with other models may result in the parameter being ignored or an error.
|
||||
|
||||
## Related Features
|
||||
|
||||
- [Extended Thinking](/docs/providers/anthropic_extended_thinking) - Control Claude's reasoning process
|
||||
- [Tool Use](/docs/providers/anthropic_tools) - Enable Claude to use tools and functions
|
||||
- [Programmatic Tool Calling](/docs/providers/anthropic_programmatic_tool_calling) - Let Claude write code that calls tools
|
||||
- [Prompt Caching](/docs/providers/anthropic_prompt_caching) - Cache prompts to reduce costs
|
||||
|
||||
## Additional Resources
|
||||
|
||||
- [Anthropic Effort Documentation](https://docs.anthropic.com/en/docs/build-with-claude/effort)
|
||||
- [LiteLLM Anthropic Provider Guide](/docs/providers/anthropic)
|
||||
- [Cost Optimization Best Practices](/docs/guides/cost_optimization)
|
||||
|
||||
|
|
@ -0,0 +1,435 @@
|
|||
# Anthropic Programmatic Tool Calling
|
||||
|
||||
Programmatic tool calling allows Claude to write code that calls your tools programmatically within a code execution container, rather than requiring round trips through the model for each tool invocation. This reduces latency for multi-tool workflows and decreases token consumption by allowing Claude to filter or process data before it reaches the model's context window.
|
||||
|
||||
:::info
|
||||
Programmatic tool calling is currently in public beta. LiteLLM automatically detects tools with the `allowed_callers` field and adds the appropriate beta header based on your provider:
|
||||
|
||||
- **Anthropic API & Microsoft Foundry**: `advanced-tool-use-2025-11-20`
|
||||
- **Amazon Bedrock**: `advanced-tool-use-2025-11-20`
|
||||
- **Google Cloud Vertex AI**: Not supported
|
||||
|
||||
This feature requires the code execution tool to be enabled.
|
||||
:::
|
||||
|
||||
## Model Compatibility
|
||||
|
||||
Programmatic tool calling is available on the following models:
|
||||
|
||||
| Model | Tool Version |
|
||||
|-------|--------------|
|
||||
| Claude Opus 4.5 (`claude-opus-4-5-20251101`) | `code_execution_20250825` |
|
||||
| Claude Sonnet 4.5 (`claude-sonnet-4-5-20250929`) | `code_execution_20250825` |
|
||||
|
||||
## Quick Start
|
||||
|
||||
Here's a simple example where Claude programmatically queries a database multiple times and aggregates results:
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-sonnet-4-5-20250929",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Query sales data for the West, East, and Central regions, then tell me which region had the highest revenue"
|
||||
}
|
||||
],
|
||||
tools=[
|
||||
{
|
||||
"type": "code_execution_20250825",
|
||||
"name": "code_execution"
|
||||
},
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "query_database",
|
||||
"description": "Execute a SQL query against the sales database. Returns a list of rows as JSON objects.",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"sql": {
|
||||
"type": "string",
|
||||
"description": "SQL query to execute"
|
||||
}
|
||||
},
|
||||
"required": ["sql"]
|
||||
}
|
||||
},
|
||||
"allowed_callers": ["code_execution_20250825"]
|
||||
}
|
||||
]
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
## How It Works
|
||||
|
||||
When you configure a tool to be callable from code execution and Claude decides to use that tool:
|
||||
|
||||
1. Claude writes Python code that invokes the tool as a function, potentially including multiple tool calls and pre/post-processing logic
|
||||
2. Claude runs this code in a sandboxed container via code execution
|
||||
3. When a tool function is called, code execution pauses and the API returns a `tool_use` block with a `caller` field
|
||||
4. You provide the tool result, and code execution continues (intermediate results are not loaded into Claude's context window)
|
||||
5. Once all code execution completes, Claude receives the final output and continues working on the task
|
||||
|
||||
This approach is particularly useful for:
|
||||
|
||||
- **Large data processing**: Filter or aggregate tool results before they reach Claude's context
|
||||
- **Multi-step workflows**: Save tokens and latency by calling tools serially or in a loop without sampling Claude in-between tool calls
|
||||
- **Conditional logic**: Make decisions based on intermediate tool results
|
||||
|
||||
## The `allowed_callers` Field
|
||||
|
||||
The `allowed_callers` field specifies which contexts can invoke a tool:
|
||||
|
||||
```python
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "query_database",
|
||||
"description": "Execute a SQL query against the database",
|
||||
"parameters": {...}
|
||||
},
|
||||
"allowed_callers": ["code_execution_20250825"]
|
||||
}
|
||||
```
|
||||
|
||||
**Possible values:**
|
||||
|
||||
- `["direct"]` - Only Claude can call this tool directly (default if omitted)
|
||||
- `["code_execution_20250825"]` - Only callable from within code execution
|
||||
- `["direct", "code_execution_20250825"]` - Callable both directly and from code execution
|
||||
|
||||
:::tip
|
||||
We recommend choosing either `["direct"]` or `["code_execution_20250825"]` for each tool rather than enabling both, as this provides clearer guidance to Claude for how best to use the tool.
|
||||
:::
|
||||
|
||||
## The `caller` Field in Responses
|
||||
|
||||
Every tool use block includes a `caller` field indicating how it was invoked:
|
||||
|
||||
**Direct invocation (traditional tool use):**
|
||||
|
||||
```python
|
||||
{
|
||||
"type": "tool_use",
|
||||
"id": "toolu_abc123",
|
||||
"name": "query_database",
|
||||
"input": {"sql": "<sql>"},
|
||||
"caller": {"type": "direct"}
|
||||
}
|
||||
```
|
||||
|
||||
**Programmatic invocation:**
|
||||
|
||||
```python
|
||||
{
|
||||
"type": "tool_use",
|
||||
"id": "toolu_xyz789",
|
||||
"name": "query_database",
|
||||
"input": {"sql": "<sql>"},
|
||||
"caller": {
|
||||
"type": "code_execution_20250825",
|
||||
"tool_id": "srvtoolu_abc123"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
The `tool_id` references the code execution tool that made the programmatic call.
|
||||
|
||||
## Container Lifecycle
|
||||
|
||||
Programmatic tool calling uses code execution containers:
|
||||
|
||||
- **Container creation**: A new container is created for each session unless you reuse an existing one
|
||||
- **Expiration**: Containers expire after approximately 4.5 minutes of inactivity (subject to change)
|
||||
- **Container ID**: Pass the `container` parameter to reuse an existing container
|
||||
- **Reuse**: Pass the container ID to maintain state across requests
|
||||
|
||||
```python
|
||||
# First request - creates a new container
|
||||
response1 = litellm.completion(
|
||||
model="anthropic/claude-sonnet-4-5-20250929",
|
||||
messages=[{"role": "user", "content": "Query the database"}],
|
||||
tools=[...]
|
||||
)
|
||||
|
||||
# Get container ID from response (if available in response metadata)
|
||||
container_id = response1.get("container", {}).get("id")
|
||||
|
||||
# Second request - reuse the same container
|
||||
response2 = litellm.completion(
|
||||
model="anthropic/claude-sonnet-4-5-20250929",
|
||||
messages=[...],
|
||||
tools=[...],
|
||||
container=container_id # Reuse container
|
||||
)
|
||||
```
|
||||
|
||||
:::warning
|
||||
When a tool is called programmatically and the container is waiting for your tool result, you must respond before the container expires. Monitor the `expires_at` field. If the container expires, Claude may treat the tool call as timed out and retry it.
|
||||
:::
|
||||
|
||||
## Example Workflow
|
||||
|
||||
### Step 1: Initial Request
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-sonnet-4-5-20250929",
|
||||
messages=[{
|
||||
"role": "user",
|
||||
"content": "Query customer purchase history from the last quarter and identify our top 5 customers by revenue"
|
||||
}],
|
||||
tools=[
|
||||
{
|
||||
"type": "code_execution_20250825",
|
||||
"name": "code_execution"
|
||||
},
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "query_database",
|
||||
"description": "Execute a SQL query against the sales database. Returns a list of rows as JSON objects.",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"sql": {"type": "string", "description": "SQL query to execute"}
|
||||
},
|
||||
"required": ["sql"]
|
||||
}
|
||||
},
|
||||
"allowed_callers": ["code_execution_20250825"]
|
||||
}
|
||||
]
|
||||
)
|
||||
```
|
||||
|
||||
### Step 2: API Response with Tool Call
|
||||
|
||||
Claude writes code that calls your tool. The response includes:
|
||||
|
||||
```python
|
||||
{
|
||||
"role": "assistant",
|
||||
"content": [
|
||||
{
|
||||
"type": "text",
|
||||
"text": "I'll query the purchase history and analyze the results."
|
||||
},
|
||||
{
|
||||
"type": "server_tool_use",
|
||||
"id": "srvtoolu_abc123",
|
||||
"name": "code_execution",
|
||||
"input": {
|
||||
"code": "results = await query_database('<sql>')\ntop_customers = sorted(results, key=lambda x: x['revenue'], reverse=True)[:5]"
|
||||
}
|
||||
},
|
||||
{
|
||||
"type": "tool_use",
|
||||
"id": "toolu_def456",
|
||||
"name": "query_database",
|
||||
"input": {"sql": "<sql>"},
|
||||
"caller": {
|
||||
"type": "code_execution_20250825",
|
||||
"tool_id": "srvtoolu_abc123"
|
||||
}
|
||||
}
|
||||
],
|
||||
"stop_reason": "tool_use"
|
||||
}
|
||||
```
|
||||
|
||||
### Step 3: Provide Tool Result
|
||||
|
||||
```python
|
||||
# Add assistant's response and tool result to conversation
|
||||
messages = [
|
||||
{"role": "user", "content": "Query customer purchase history..."},
|
||||
{
|
||||
"role": "assistant",
|
||||
"content": response.choices[0].message.content,
|
||||
"tool_calls": response.choices[0].message.tool_calls
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "tool_result",
|
||||
"tool_use_id": "toolu_def456",
|
||||
"content": '[{"customer_id": "C1", "revenue": 45000}, ...]'
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
|
||||
# Continue the conversation
|
||||
response2 = litellm.completion(
|
||||
model="anthropic/claude-sonnet-4-5-20250929",
|
||||
messages=messages,
|
||||
tools=[...]
|
||||
)
|
||||
```
|
||||
|
||||
### Step 4: Final Response
|
||||
|
||||
Once code execution completes, Claude provides the final response:
|
||||
|
||||
```python
|
||||
{
|
||||
"content": [
|
||||
{
|
||||
"type": "code_execution_tool_result",
|
||||
"tool_use_id": "srvtoolu_abc123",
|
||||
"content": {
|
||||
"type": "code_execution_result",
|
||||
"stdout": "Top 5 customers by revenue:\n1. Customer C1: $45,000\n...",
|
||||
"stderr": "",
|
||||
"return_code": 0
|
||||
}
|
||||
},
|
||||
{
|
||||
"type": "text",
|
||||
"text": "I've analyzed the purchase history from last quarter. Your top 5 customers generated $167,500 in total revenue..."
|
||||
}
|
||||
],
|
||||
"stop_reason": "end_turn"
|
||||
}
|
||||
```
|
||||
|
||||
## Advanced Patterns
|
||||
|
||||
### Batch Processing with Loops
|
||||
|
||||
Claude can write code that processes multiple items efficiently:
|
||||
|
||||
```python
|
||||
# Claude writes code like this:
|
||||
regions = ["West", "East", "Central", "North", "South"]
|
||||
results = {}
|
||||
for region in regions:
|
||||
data = await query_database(f"SELECT SUM(revenue) FROM sales WHERE region='{region}'")
|
||||
results[region] = data[0]["total"]
|
||||
|
||||
top_region = max(results.items(), key=lambda x: x[1])
|
||||
print(f"Top region: {top_region[0]} with ${top_region[1]:,}")
|
||||
```
|
||||
|
||||
This pattern:
|
||||
- Reduces model round-trips from N (one per region) to 1
|
||||
- Processes large result sets programmatically before returning to Claude
|
||||
- Saves tokens by only returning aggregated conclusions
|
||||
|
||||
### Early Termination
|
||||
|
||||
Claude can stop processing as soon as success criteria are met:
|
||||
|
||||
```python
|
||||
endpoints = ["us-east", "eu-west", "apac"]
|
||||
for endpoint in endpoints:
|
||||
status = await check_health(endpoint)
|
||||
if status == "healthy":
|
||||
print(f"Found healthy endpoint: {endpoint}")
|
||||
break # Stop early
|
||||
```
|
||||
|
||||
### Data Filtering
|
||||
|
||||
```python
|
||||
logs = await fetch_logs(server_id)
|
||||
errors = [log for log in logs if "ERROR" in log]
|
||||
print(f"Found {len(errors)} errors")
|
||||
for error in errors[-10:]: # Only return last 10 errors
|
||||
print(error)
|
||||
```
|
||||
|
||||
## Best Practices
|
||||
|
||||
### Tool Design
|
||||
|
||||
- **Provide detailed output descriptions**: Since Claude deserializes tool results in code, clearly document the format (JSON structure, field types, etc.)
|
||||
- **Return structured data**: JSON or other easily parseable formats work best for programmatic processing
|
||||
- **Keep responses concise**: Return only necessary data to minimize processing overhead
|
||||
|
||||
### When to Use Programmatic Calling
|
||||
|
||||
**Good use cases:**
|
||||
|
||||
- Processing large datasets where you only need aggregates or summaries
|
||||
- Multi-step workflows with 3+ dependent tool calls
|
||||
- Operations requiring filtering, sorting, or transformation of tool results
|
||||
- Tasks where intermediate data shouldn't influence Claude's reasoning
|
||||
- Parallel operations across many items (e.g., checking 50 endpoints)
|
||||
|
||||
**Less ideal use cases:**
|
||||
|
||||
- Single tool calls with simple responses
|
||||
- Tools that need immediate user feedback
|
||||
- Very fast operations where code execution overhead would outweigh the benefit
|
||||
|
||||
## Token Efficiency
|
||||
|
||||
Programmatic tool calling can significantly reduce token consumption:
|
||||
|
||||
- **Tool results from programmatic calls are not added to Claude's context** - only the final code output is
|
||||
- **Intermediate processing happens in code** - filtering, aggregation, etc. don't consume model tokens
|
||||
- **Multiple tool calls in one code execution** - reduces overhead compared to separate model turns
|
||||
|
||||
For example, calling 10 tools directly uses ~10x the tokens of calling them programmatically and returning a summary.
|
||||
|
||||
## Provider Support
|
||||
|
||||
LiteLLM supports programmatic tool calling across the following Anthropic-compatible providers:
|
||||
|
||||
- **Standard Anthropic API** (`anthropic/claude-sonnet-4-5-20250929`) ✅
|
||||
- **Azure Anthropic / Microsoft Foundry** (`azure/claude-sonnet-4-5-20250929`) ✅
|
||||
- **Amazon Bedrock** (`bedrock/invoke/anthropic.claude-sonnet-4-5-20250929-v1:0`) ✅
|
||||
- **Google Cloud Vertex AI** (`vertex_ai/claude-sonnet-4-5-20250929`) ❌ Not supported
|
||||
|
||||
The beta header (`advanced-tool-use-2025-11-20`) is automatically added when LiteLLM detects tools with the `allowed_callers` field.
|
||||
|
||||
## Limitations
|
||||
|
||||
### Feature Incompatibilities
|
||||
|
||||
- **Structured outputs**: Tools with `strict: true` are not supported with programmatic calling
|
||||
- **Tool choice**: You cannot force programmatic calling of a specific tool via `tool_choice`
|
||||
- **Parallel tool use**: `disable_parallel_tool_use: true` is not supported with programmatic calling
|
||||
|
||||
### Tool Restrictions
|
||||
|
||||
The following tools cannot currently be called programmatically:
|
||||
|
||||
- Web search
|
||||
- Web fetch
|
||||
- Tools provided by an MCP connector
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
### Common Issues
|
||||
|
||||
**"Tool not allowed" error**
|
||||
|
||||
- Verify your tool definition includes `"allowed_callers": ["code_execution_20250825"]`
|
||||
- Check that you're using a compatible model (Claude Sonnet 4.5 or Opus 4.5)
|
||||
|
||||
**Container expiration**
|
||||
|
||||
- Ensure you respond to tool calls within the container's lifetime (~4.5 minutes)
|
||||
- Consider implementing faster tool execution
|
||||
|
||||
**Beta header not added**
|
||||
|
||||
- LiteLLM automatically adds the beta header when it detects `allowed_callers`
|
||||
- If you're manually setting headers, ensure you include `advanced-tool-use-2025-11-20`
|
||||
|
||||
## Related Features
|
||||
|
||||
- [Anthropic Tool Search](./anthropic_tool_search.md) - Dynamically discover and load tools on-demand
|
||||
- [Anthropic Provider](./anthropic.md) - General Anthropic provider documentation
|
||||
|
||||
445
docs/my-website/docs/providers/anthropic_tool_input_examples.md
Normal file
445
docs/my-website/docs/providers/anthropic_tool_input_examples.md
Normal file
|
|
@ -0,0 +1,445 @@
|
|||
# Anthropic Tool Input Examples
|
||||
|
||||
Provide concrete examples of valid tool inputs to help Claude understand how to use your tools more effectively. This is particularly useful for complex tools with nested objects, optional parameters, or format-sensitive inputs.
|
||||
|
||||
:::info
|
||||
Tool input examples is a beta feature. LiteLLM automatically detects tools with the `input_examples` field and adds the appropriate beta header based on your provider:
|
||||
|
||||
- **Anthropic API & Microsoft Foundry**: `advanced-tool-use-2025-11-20`
|
||||
- **Amazon Bedrock**: `advanced-tool-use-2025-11-20` (Claude Opus 4.5 only)
|
||||
- **Google Cloud Vertex AI**: Not supported
|
||||
|
||||
You don't need to manually specify beta headers—LiteLLM handles this automatically.
|
||||
:::
|
||||
|
||||
## When to Use Input Examples
|
||||
|
||||
Input examples are most helpful for:
|
||||
|
||||
- **Complex nested objects**: Tools with deeply nested parameter structures
|
||||
- **Optional parameters**: Showing when optional parameters should be included
|
||||
- **Format-sensitive inputs**: Demonstrating expected formats (dates, addresses, etc.)
|
||||
- **Enum values**: Illustrating valid enum choices in context
|
||||
- **Edge cases**: Showing how to handle special cases
|
||||
|
||||
:::tip
|
||||
**Prioritize descriptions first!** Clear, detailed tool descriptions are more important than examples. Use `input_examples` as a supplement for complex tools where descriptions alone may not be sufficient.
|
||||
:::
|
||||
|
||||
## Quick Start
|
||||
|
||||
Add an `input_examples` field to your tool definition with an array of example input objects:
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-sonnet-4-5-20250929",
|
||||
messages=[
|
||||
{"role": "user", "content": "What's the weather like in San Francisco?"}
|
||||
],
|
||||
tools=[
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get the current weather in a given location",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {
|
||||
"type": "string",
|
||||
"description": "The city and state, e.g. San Francisco, CA"
|
||||
},
|
||||
"unit": {
|
||||
"type": "string",
|
||||
"enum": ["celsius", "fahrenheit"],
|
||||
"description": "The unit of temperature"
|
||||
}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
},
|
||||
"input_examples": [
|
||||
{
|
||||
"location": "San Francisco, CA",
|
||||
"unit": "fahrenheit"
|
||||
},
|
||||
{
|
||||
"location": "Tokyo, Japan",
|
||||
"unit": "celsius"
|
||||
},
|
||||
{
|
||||
"location": "New York, NY" # 'unit' is optional
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
## How It Works
|
||||
|
||||
When you provide `input_examples`:
|
||||
|
||||
1. **LiteLLM detects** the `input_examples` field in your tool definition
|
||||
2. **Beta header added automatically**: The `advanced-tool-use-2025-11-20` header is injected
|
||||
3. **Examples included in prompt**: Anthropic includes the examples alongside your tool schema
|
||||
4. **Claude learns patterns**: The model uses examples to understand proper tool usage
|
||||
5. **Better tool calls**: Claude makes more accurate tool calls with correct parameter formats
|
||||
|
||||
## Example Formats
|
||||
|
||||
### Simple Tool with Examples
|
||||
|
||||
```python
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "send_email",
|
||||
"description": "Send an email to a recipient",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"to": {"type": "string", "description": "Email address"},
|
||||
"subject": {"type": "string"},
|
||||
"body": {"type": "string"}
|
||||
},
|
||||
"required": ["to", "subject", "body"]
|
||||
}
|
||||
},
|
||||
"input_examples": [
|
||||
{
|
||||
"to": "user@example.com",
|
||||
"subject": "Meeting Reminder",
|
||||
"body": "Don't forget our meeting tomorrow at 2 PM."
|
||||
},
|
||||
{
|
||||
"to": "team@company.com",
|
||||
"subject": "Weekly Update",
|
||||
"body": "Here's this week's progress report..."
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
### Complex Nested Objects
|
||||
|
||||
```python
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "create_calendar_event",
|
||||
"description": "Create a new calendar event",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"title": {"type": "string"},
|
||||
"start": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"date": {"type": "string"},
|
||||
"time": {"type": "string"}
|
||||
}
|
||||
},
|
||||
"attendees": {
|
||||
"type": "array",
|
||||
"items": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"email": {"type": "string"},
|
||||
"optional": {"type": "boolean"}
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
"required": ["title", "start"]
|
||||
}
|
||||
},
|
||||
"input_examples": [
|
||||
{
|
||||
"title": "Team Standup",
|
||||
"start": {
|
||||
"date": "2025-01-15",
|
||||
"time": "09:00"
|
||||
},
|
||||
"attendees": [
|
||||
{"email": "alice@example.com", "optional": False},
|
||||
{"email": "bob@example.com", "optional": True}
|
||||
]
|
||||
},
|
||||
{
|
||||
"title": "Lunch Break",
|
||||
"start": {
|
||||
"date": "2025-01-15",
|
||||
"time": "12:00"
|
||||
}
|
||||
# No attendees - showing optional field
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
### Format-Sensitive Parameters
|
||||
|
||||
```python
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "search_flights",
|
||||
"description": "Search for available flights",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"origin": {"type": "string", "description": "Airport code"},
|
||||
"destination": {"type": "string", "description": "Airport code"},
|
||||
"date": {"type": "string", "description": "Date in YYYY-MM-DD format"},
|
||||
"passengers": {"type": "integer"}
|
||||
},
|
||||
"required": ["origin", "destination", "date"]
|
||||
}
|
||||
},
|
||||
"input_examples": [
|
||||
{
|
||||
"origin": "SFO",
|
||||
"destination": "JFK",
|
||||
"date": "2025-03-15",
|
||||
"passengers": 2
|
||||
},
|
||||
{
|
||||
"origin": "LAX",
|
||||
"destination": "ORD",
|
||||
"date": "2025-04-20",
|
||||
"passengers": 1
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
## Requirements and Limitations
|
||||
|
||||
### Schema Validation
|
||||
|
||||
- Each example **must be valid** according to the tool's `input_schema`
|
||||
- Invalid examples will return a **400 error** from Anthropic
|
||||
- Validation happens server-side (LiteLLM passes examples through)
|
||||
|
||||
### Server-Side Tools Not Supported
|
||||
|
||||
Input examples are **only supported for user-defined tools**. The following server-side tools do NOT support `input_examples`:
|
||||
|
||||
- `web_search` (web search tool)
|
||||
- `code_execution` (code execution tool)
|
||||
- `computer_use` (computer use tool)
|
||||
- `bash_tool` (bash execution tool)
|
||||
- `text_editor` (text editor tool)
|
||||
|
||||
### Token Costs
|
||||
|
||||
Examples add to your prompt tokens:
|
||||
|
||||
- **Simple examples**: ~20-50 tokens per example
|
||||
- **Complex nested objects**: ~100-200 tokens per example
|
||||
- **Trade-off**: Higher token cost for better tool call accuracy
|
||||
|
||||
### Model Compatibility
|
||||
|
||||
Input examples work with all Claude models that support the `advanced-tool-use-2025-11-20` beta header:
|
||||
|
||||
- Claude Opus 4.5 (`claude-opus-4-5-20251101`)
|
||||
- Claude Sonnet 4.5 (`claude-sonnet-4-5-20250929`)
|
||||
- Claude Opus 4.1 (`claude-opus-4-1-20250805`)
|
||||
|
||||
:::note
|
||||
On Google Cloud's Vertex AI and Amazon Bedrock, only Claude Opus 4.5 supports tool input examples.
|
||||
:::
|
||||
|
||||
## Best Practices
|
||||
|
||||
### 1. Show Diverse Examples
|
||||
|
||||
Include examples that demonstrate different use cases:
|
||||
|
||||
```python
|
||||
"input_examples": [
|
||||
{"location": "San Francisco, CA", "unit": "fahrenheit"}, # US city
|
||||
{"location": "Tokyo, Japan", "unit": "celsius"}, # International
|
||||
{"location": "New York, NY"} # Optional param omitted
|
||||
]
|
||||
```
|
||||
|
||||
### 2. Demonstrate Optional Parameters
|
||||
|
||||
Show when optional parameters should and shouldn't be included:
|
||||
|
||||
```python
|
||||
"input_examples": [
|
||||
{
|
||||
"query": "machine learning",
|
||||
"filters": {"year": 2024, "category": "research"} # With optional filters
|
||||
},
|
||||
{
|
||||
"query": "artificial intelligence" # Without optional filters
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
### 3. Illustrate Format Requirements
|
||||
|
||||
Make format expectations clear through examples:
|
||||
|
||||
```python
|
||||
"input_examples": [
|
||||
{
|
||||
"phone": "+1-555-123-4567", # Shows expected phone format
|
||||
"date": "2025-01-15", # Shows date format (YYYY-MM-DD)
|
||||
"time": "14:30" # Shows time format (HH:MM)
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
### 4. Keep Examples Realistic
|
||||
|
||||
Use realistic, production-like examples rather than placeholder data:
|
||||
|
||||
```python
|
||||
# ✅ Good - realistic examples
|
||||
"input_examples": [
|
||||
{"email": "alice@company.com", "role": "admin"},
|
||||
{"email": "bob@company.com", "role": "user"}
|
||||
]
|
||||
|
||||
# ❌ Bad - placeholder examples
|
||||
"input_examples": [
|
||||
{"email": "test@test.com", "role": "role1"},
|
||||
{"email": "example@example.com", "role": "role2"}
|
||||
]
|
||||
```
|
||||
|
||||
### 5. Limit Example Count
|
||||
|
||||
Provide 2-5 examples per tool:
|
||||
|
||||
- **Too few** (1): May not show enough variation
|
||||
- **Just right** (2-5): Demonstrates patterns without bloating tokens
|
||||
- **Too many** (10+): Wastes tokens, diminishing returns
|
||||
|
||||
## Integration with Other Features
|
||||
|
||||
Input examples work seamlessly with other Anthropic tool features:
|
||||
|
||||
### With Tool Search
|
||||
|
||||
```python
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "query_database",
|
||||
"description": "Execute a SQL query",
|
||||
"parameters": {...}
|
||||
},
|
||||
"defer_loading": True, # Tool search
|
||||
"input_examples": [ # Input examples
|
||||
{"sql": "SELECT * FROM users WHERE id = 1"}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
### With Programmatic Tool Calling
|
||||
|
||||
```python
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "fetch_data",
|
||||
"description": "Fetch data from API",
|
||||
"parameters": {...}
|
||||
},
|
||||
"allowed_callers": ["code_execution_20250825"], # Programmatic calling
|
||||
"input_examples": [ # Input examples
|
||||
{"endpoint": "/api/users", "method": "GET"}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
### All Features Combined
|
||||
|
||||
```python
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "advanced_tool",
|
||||
"description": "A complex tool",
|
||||
"parameters": {...}
|
||||
},
|
||||
"defer_loading": True, # Tool search
|
||||
"allowed_callers": ["code_execution_20250825"], # Programmatic calling
|
||||
"input_examples": [ # Input examples
|
||||
{"param1": "value1", "param2": "value2"}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
## Provider Support
|
||||
|
||||
LiteLLM supports input examples across the following Anthropic-compatible providers:
|
||||
|
||||
- **Standard Anthropic API** (`anthropic/claude-sonnet-4-5-20250929`) ✅
|
||||
- **Azure Anthropic / Microsoft Foundry** (`azure/claude-sonnet-4-5-20250929`) ✅
|
||||
- **Amazon Bedrock** (`bedrock/invoke/anthropic.claude-opus-4-5-20251101-v1:0`) ✅ (Opus 4.5 only)
|
||||
- **Google Cloud Vertex AI** (`vertex_ai/claude-sonnet-4-5-20250929`) ❌ Not supported
|
||||
|
||||
The beta header (`advanced-tool-use-2025-11-20`) is automatically added when LiteLLM detects tools with the `input_examples` field.
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
### "Invalid request" error with examples
|
||||
|
||||
**Problem**: Receiving 400 error when using input examples
|
||||
|
||||
**Solution**: Ensure each example is valid according to your `input_schema`:
|
||||
|
||||
```python
|
||||
# Check that:
|
||||
# 1. All required fields are present in examples
|
||||
# 2. Field types match the schema
|
||||
# 3. Enum values are valid
|
||||
# 4. Nested objects follow the schema structure
|
||||
```
|
||||
|
||||
### Examples not improving tool calls
|
||||
|
||||
**Problem**: Adding examples doesn't seem to help
|
||||
|
||||
**Solution**:
|
||||
1. **Check descriptions first**: Ensure tool descriptions are detailed and clear
|
||||
2. **Review example quality**: Make sure examples are realistic and diverse
|
||||
3. **Verify schema**: Confirm examples actually match your schema
|
||||
4. **Add more variation**: Include examples showing different use cases
|
||||
|
||||
### Token usage too high
|
||||
|
||||
**Problem**: Input examples consuming too many tokens
|
||||
|
||||
**Solution**:
|
||||
1. **Reduce example count**: Use 2-3 examples instead of 5+
|
||||
2. **Simplify examples**: Remove unnecessary fields from examples
|
||||
3. **Consider descriptions**: If descriptions are clear, examples may not be needed
|
||||
|
||||
## When NOT to Use Input Examples
|
||||
|
||||
Skip input examples if:
|
||||
|
||||
- **Tool is simple**: Single parameter tools with clear descriptions
|
||||
- **Schema is self-explanatory**: Well-structured schema with good descriptions
|
||||
- **Token budget is tight**: Examples add 20-200 tokens each
|
||||
- **Server-side tools**: web_search, code_execution, etc. don't support examples
|
||||
|
||||
## Related Features
|
||||
|
||||
- [Anthropic Tool Search](./anthropic_tool_search.md) - Dynamically discover and load tools on-demand
|
||||
- [Anthropic Programmatic Tool Calling](./anthropic_programmatic_tool_calling.md) - Call tools from code execution
|
||||
- [Anthropic Provider](./anthropic.md) - General Anthropic provider documentation
|
||||
|
||||
412
docs/my-website/docs/providers/anthropic_tool_search.md
Normal file
412
docs/my-website/docs/providers/anthropic_tool_search.md
Normal file
|
|
@ -0,0 +1,412 @@
|
|||
# Anthropic Tool Search
|
||||
|
||||
Tool search enables Claude to dynamically discover and load tools on-demand from large tool catalogs (10,000+ tools). Instead of loading all tool definitions into the context window upfront, Claude searches your tool catalog and loads only the tools it needs.
|
||||
|
||||
## Benefits
|
||||
|
||||
- **Context efficiency**: Avoid consuming massive portions of your context window with tool definitions
|
||||
- **Better tool selection**: Claude's tool selection accuracy degrades with more than 30-50 tools. Tool search maintains accuracy even with thousands of tools
|
||||
- **On-demand loading**: Tools are only loaded when Claude needs them
|
||||
|
||||
## Supported Models
|
||||
|
||||
Tool search is available on:
|
||||
- Claude Opus 4.5
|
||||
- Claude Sonnet 4.5
|
||||
|
||||
## Supported Platforms
|
||||
|
||||
- Anthropic API (direct)
|
||||
- Azure Anthropic (Microsoft Foundry)
|
||||
- Google Cloud Vertex AI
|
||||
- Amazon Bedrock (invoke API only, not converse API)
|
||||
|
||||
## Tool Search Variants
|
||||
|
||||
LiteLLM supports both tool search variants:
|
||||
|
||||
### 1. Regex Tool Search (`tool_search_tool_regex_20251119`)
|
||||
|
||||
Claude constructs regex patterns to search for tools.
|
||||
|
||||
### 2. BM25 Tool Search (`tool_search_tool_bm25_20251119`)
|
||||
|
||||
Claude uses natural language queries to search for tools using the BM25 algorithm.
|
||||
|
||||
## Quick Start
|
||||
|
||||
### Basic Example with Regex Tool Search
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-sonnet-4-5-20250929",
|
||||
messages=[
|
||||
{"role": "user", "content": "What is the weather in San Francisco?"}
|
||||
],
|
||||
tools=[
|
||||
# Tool search tool (regex variant)
|
||||
{
|
||||
"type": "tool_search_tool_regex_20251119",
|
||||
"name": "tool_search_tool_regex"
|
||||
},
|
||||
# Deferred tool - will be loaded on-demand
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get the weather at a specific location",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {"type": "string"},
|
||||
"unit": {
|
||||
"type": "string",
|
||||
"enum": ["celsius", "fahrenheit"]
|
||||
}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
},
|
||||
"defer_loading": True # Mark for deferred loading
|
||||
},
|
||||
# Another deferred tool
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "search_files",
|
||||
"description": "Search through files in the workspace",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"query": {"type": "string"},
|
||||
"file_types": {
|
||||
"type": "array",
|
||||
"items": {"type": "string"}
|
||||
}
|
||||
},
|
||||
"required": ["query"]
|
||||
}
|
||||
},
|
||||
"defer_loading": True
|
||||
}
|
||||
]
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
### BM25 Tool Search Example
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-sonnet-4-5-20250929",
|
||||
messages=[
|
||||
{"role": "user", "content": "Search for Python files containing 'authentication'"}
|
||||
],
|
||||
tools=[
|
||||
# Tool search tool (BM25 variant)
|
||||
{
|
||||
"type": "tool_search_tool_bm25_20251119",
|
||||
"name": "tool_search_tool_bm25"
|
||||
},
|
||||
# Deferred tools...
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "search_codebase",
|
||||
"description": "Search through codebase files by content and filename",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"query": {"type": "string"},
|
||||
"file_pattern": {"type": "string"}
|
||||
},
|
||||
"required": ["query"]
|
||||
}
|
||||
},
|
||||
"defer_loading": True
|
||||
}
|
||||
]
|
||||
)
|
||||
```
|
||||
|
||||
## Using with Azure Anthropic
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="azure_anthropic/claude-sonnet-4-5",
|
||||
api_base="https://<your-resource>.services.ai.azure.com/anthropic",
|
||||
api_key="your-azure-api-key",
|
||||
messages=[
|
||||
{"role": "user", "content": "What's the weather like?"}
|
||||
],
|
||||
tools=[
|
||||
{
|
||||
"type": "tool_search_tool_regex_20251119",
|
||||
"name": "tool_search_tool_regex"
|
||||
},
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get current weather",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {"type": "string"}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
},
|
||||
"defer_loading": True
|
||||
}
|
||||
]
|
||||
)
|
||||
```
|
||||
|
||||
## Using with Vertex AI
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="vertex_ai/claude-sonnet-4-5",
|
||||
vertex_project="your-project-id",
|
||||
vertex_location="us-central1",
|
||||
messages=[
|
||||
{"role": "user", "content": "Search my documents"}
|
||||
],
|
||||
tools=[
|
||||
{
|
||||
"type": "tool_search_tool_bm25_20251119",
|
||||
"name": "tool_search_tool_bm25"
|
||||
},
|
||||
# Your deferred tools...
|
||||
]
|
||||
)
|
||||
```
|
||||
|
||||
## Streaming Support
|
||||
|
||||
Tool search works with streaming:
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-sonnet-4-5-20250929",
|
||||
messages=[
|
||||
{"role": "user", "content": "Get the weather"}
|
||||
],
|
||||
tools=[
|
||||
{
|
||||
"type": "tool_search_tool_regex_20251119",
|
||||
"name": "tool_search_tool_regex"
|
||||
},
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get weather information",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {"type": "string"}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
},
|
||||
"defer_loading": True
|
||||
}
|
||||
],
|
||||
stream=True
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
if chunk.choices[0].delta.content:
|
||||
print(chunk.choices[0].delta.content, end="")
|
||||
```
|
||||
|
||||
## LiteLLM Proxy
|
||||
|
||||
Tool search works automatically through the LiteLLM proxy:
|
||||
|
||||
### Proxy Config
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-sonnet
|
||||
litellm_params:
|
||||
model: anthropic/claude-sonnet-4-5-20250929
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
```
|
||||
|
||||
### Client Request
|
||||
|
||||
```python
|
||||
import openai
|
||||
|
||||
client = openai.OpenAI(
|
||||
api_key="your-litellm-proxy-key",
|
||||
base_url="http://0.0.0.0:4000"
|
||||
)
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="claude-sonnet",
|
||||
messages=[
|
||||
{"role": "user", "content": "What's the weather?"}
|
||||
],
|
||||
tools=[
|
||||
{
|
||||
"type": "tool_search_tool_regex_20251119",
|
||||
"name": "tool_search_tool_regex"
|
||||
},
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get weather information",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {"type": "string"}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
},
|
||||
"defer_loading": True
|
||||
}
|
||||
]
|
||||
)
|
||||
```
|
||||
|
||||
## Important Notes
|
||||
|
||||
### Beta Header
|
||||
|
||||
LiteLLM automatically detects tool search tools and adds the appropriate beta header based on your provider:
|
||||
|
||||
- **Anthropic API & Microsoft Foundry**: `advanced-tool-use-2025-11-20`
|
||||
- **Google Cloud Vertex AI**: `tool-search-tool-2025-10-19`
|
||||
- **Amazon Bedrock** (Invoke API, Opus 4.5 only): `tool-search-tool-2025-10-19`
|
||||
|
||||
You don't need to manually specify beta headers—LiteLLM handles this automatically.
|
||||
|
||||
### Deferred Loading
|
||||
|
||||
- Tools with `defer_loading: true` are only loaded when Claude discovers them via search
|
||||
- At least one tool must be non-deferred (the tool search tool itself)
|
||||
- Keep your 3-5 most frequently used tools as non-deferred for optimal performance
|
||||
|
||||
### Tool Descriptions
|
||||
|
||||
Write clear, descriptive tool names and descriptions that match how users describe tasks. The search algorithm uses:
|
||||
- Tool names
|
||||
- Tool descriptions
|
||||
- Argument names
|
||||
- Argument descriptions
|
||||
|
||||
### Usage Tracking
|
||||
|
||||
Tool search requests are tracked in the usage object:
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-sonnet-4-5-20250929",
|
||||
messages=[{"role": "user", "content": "Search for tools"}],
|
||||
tools=[...]
|
||||
)
|
||||
|
||||
# Check tool search usage
|
||||
if response.usage.server_tool_use:
|
||||
print(f"Tool search requests: {response.usage.server_tool_use.tool_search_requests}")
|
||||
```
|
||||
|
||||
## Error Handling
|
||||
|
||||
### All Tools Deferred
|
||||
|
||||
```python
|
||||
# ❌ This will fail - at least one tool must be non-deferred
|
||||
tools = [
|
||||
{
|
||||
"type": "function",
|
||||
"function": {...},
|
||||
"defer_loading": True
|
||||
}
|
||||
]
|
||||
|
||||
# ✅ Correct - tool search tool is non-deferred
|
||||
tools = [
|
||||
{
|
||||
"type": "tool_search_tool_regex_20251119",
|
||||
"name": "tool_search_tool_regex"
|
||||
},
|
||||
{
|
||||
"type": "function",
|
||||
"function": {...},
|
||||
"defer_loading": True
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
### Missing Tool Definition
|
||||
|
||||
If Claude references a tool that isn't in your deferred tools list, you'll get an error. Make sure all tools that might be discovered are included in the tools parameter with `defer_loading: true`.
|
||||
|
||||
## Best Practices
|
||||
|
||||
1. **Keep frequently used tools non-deferred**: Your 3-5 most common tools should not have `defer_loading: true`
|
||||
|
||||
2. **Use semantic descriptions**: Tool descriptions should use natural language that matches user queries
|
||||
|
||||
3. **Choose the right variant**:
|
||||
- Use **regex** for exact pattern matching (faster)
|
||||
- Use **BM25** for natural language semantic search
|
||||
|
||||
4. **Monitor usage**: Track `tool_search_requests` in the usage object to understand search patterns
|
||||
|
||||
5. **Optimize tool catalog**: Remove unused tools and consolidate similar functionality
|
||||
|
||||
## When to Use Tool Search
|
||||
|
||||
**Good use cases:**
|
||||
- 10+ tools available in your system
|
||||
- Tool definitions consuming >10K tokens
|
||||
- Experiencing tool selection accuracy issues
|
||||
- Building systems with multiple tool categories
|
||||
- Tool library growing over time
|
||||
|
||||
**When traditional tool calling is better:**
|
||||
- Less than 10 tools total
|
||||
- All tools are frequently used
|
||||
- Very small tool definitions (\<100 tokens total)
|
||||
|
||||
## Limitations
|
||||
|
||||
- Not compatible with tool use examples
|
||||
- Requires Claude Opus 4.5 or Sonnet 4.5
|
||||
- On Bedrock, only available via invoke API (not converse API)
|
||||
- On Bedrock, only supported for Claude Opus 4.5 (not Sonnet 4.5)
|
||||
- BM25 variant (`tool_search_tool_bm25_20251119`) is not supported on Bedrock
|
||||
- Maximum 10,000 tools in catalog
|
||||
- Returns 3-5 most relevant tools per search
|
||||
|
||||
### Bedrock-Specific Notes
|
||||
|
||||
When using Bedrock's Invoke API:
|
||||
- The regex variant (`tool_search_tool_regex_20251119`) is automatically normalized to `tool_search_tool_regex`
|
||||
- The BM25 variant (`tool_search_tool_bm25_20251119`) is automatically filtered out as it's not supported
|
||||
- Tool search is only available for Claude Opus 4.5 models
|
||||
|
||||
## Additional Resources
|
||||
|
||||
- [Anthropic Tool Search Documentation](https://docs.anthropic.com/en/docs/build-with-claude/tool-use/tool-search)
|
||||
- [LiteLLM Tool Calling Guide](https://docs.litellm.ai/docs/completion/function_call)
|
||||
|
||||
|
|
@ -9,10 +9,10 @@ import TabItem from '@theme/TabItem';
|
|||
|
||||
| Property | Details |
|
||||
|-------|-------|
|
||||
| Description | Azure OpenAI Service provides REST API access to OpenAI's powerful language models including o1, o1-mini, GPT-5, GPT-4o, GPT-4o mini, GPT-4 Turbo with Vision, GPT-4, GPT-3.5-Turbo, and Embeddings model series |
|
||||
| Provider Route on LiteLLM | `azure/`, [`azure/o_series/`](#o-series-models), [`azure/gpt5_series/`](#gpt-5-models) |
|
||||
| Supported Operations | [`/chat/completions`](#azure-openai-chat-completion-models), [`/responses`](./azure_responses), [`/completions`](#azure-instruct-models), [`/embeddings`](./azure_embedding), [`/audio/speech`](azure_speech), [`/audio/transcriptions`](../audio_transcription), `/fine_tuning`, [`/batches`](#azure-batches-api), `/files`, [`/images`](../image_generation#azure-openai-image-generation-models) |
|
||||
| Link to Provider Doc | [Azure OpenAI ↗](https://learn.microsoft.com/en-us/azure/ai-services/openai/overview)
|
||||
| Description | Azure OpenAI Service provides REST API access to OpenAI's powerful language models including o1, o1-mini, GPT-5, GPT-4o, GPT-4o mini, GPT-4 Turbo with Vision, GPT-4, GPT-3.5-Turbo, and Embeddings model series. Also supports Claude models via Azure Foundry. |
|
||||
| Provider Route on LiteLLM | `azure/`, [`azure/o_series/`](#o-series-models), [`azure/gpt5_series/`](#gpt-5-models), [`azure/claude-*`](./azure_anthropic) (Claude models via Azure Foundry) |
|
||||
| Supported Operations | [`/chat/completions`](#azure-openai-chat-completion-models), [`/responses`](./azure_responses), [`/completions`](#azure-instruct-models), [`/embeddings`](./azure_embedding), [`/audio/speech`](azure_speech), [`/audio/transcriptions`](../audio_transcription), `/fine_tuning`, [`/batches`](#azure-batches-api), `/files`, [`/images`](../image_generation#azure-openai-image-generation-models), [`/anthropic/v1/messages`](./azure_anthropic) |
|
||||
| Link to Provider Doc | [Azure OpenAI ↗](https://learn.microsoft.com/en-us/azure/ai-services/openai/overview), [Azure Foundry Claude ↗](https://learn.microsoft.com/en-us/azure/ai-services/foundry-models/claude)
|
||||
|
||||
## API Keys, Params
|
||||
api_key, api_base, api_version etc can be passed directly to `litellm.completion` - see here or set as `litellm.api_key` params see here
|
||||
|
|
@ -27,6 +27,12 @@ os.environ["AZURE_AD_TOKEN"] = ""
|
|||
os.environ["AZURE_API_TYPE"] = ""
|
||||
```
|
||||
|
||||
:::info Azure Foundry Claude Models
|
||||
|
||||
Azure also supports Claude models via Azure Foundry. Use `azure/claude-*` model names (e.g., `azure/claude-sonnet-4-5`) with Azure authentication. See the [Azure Anthropic documentation](./azure_anthropic) for details.
|
||||
|
||||
:::
|
||||
|
||||
## **Usage - LiteLLM Python SDK**
|
||||
<a target="_blank" href="https://colab.research.google.com/github/BerriAI/litellm/blob/main/cookbook/LiteLLM_Azure_OpenAI.ipynb">
|
||||
<img src="https://colab.research.google.com/assets/colab-badge.svg" alt="Open In Colab"/>
|
||||
|
|
@ -251,7 +257,7 @@ response = completion(
|
|||
{
|
||||
"type": "image_url",
|
||||
"image_url": {
|
||||
"url": "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg"
|
||||
"url": "https://awsmp-logos.s3.amazonaws.com/seller-xw5kijmvmzasy/c233c9ade2ccb5491072ae232c814942.png"
|
||||
}
|
||||
}
|
||||
]
|
||||
|
|
@ -543,7 +549,8 @@ print(response)
|
|||
|
||||
### Entra ID - use `azure_ad_token`
|
||||
|
||||
This is a walkthrough on how to use Azure Active Directory Tokens - Microsoft Entra ID to make `litellm.completion()` calls
|
||||
This is a walkthrough on how to use Azure Active Directory Tokens - Microsoft Entra ID to make `litellm.completion()` calls.
|
||||
> **Note:** You can follow the same process below to use Azure Active Directory Tokens for all other Azure endpoints (e.g., chat, embeddings, image, audio, etc.) with LiteLLM.
|
||||
|
||||
Step 1 - Download Azure CLI
|
||||
Installation instructions: https://learn.microsoft.com/en-us/cli/azure/install-azure-cli
|
||||
|
|
|
|||
378
docs/my-website/docs/providers/azure/azure_anthropic.md
Normal file
378
docs/my-website/docs/providers/azure/azure_anthropic.md
Normal file
|
|
@ -0,0 +1,378 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Azure Anthropic (Claude via Azure Foundry)
|
||||
|
||||
LiteLLM supports Claude models deployed via Microsoft Azure Foundry, including Claude Sonnet 4.5, Claude Haiku 4.5, and Claude Opus 4.1.
|
||||
|
||||
## Available Models
|
||||
|
||||
Azure Foundry supports the following Claude models:
|
||||
|
||||
- `claude-sonnet-4-5` - Anthropic's most capable model for building real-world agents and handling complex, long-horizon tasks
|
||||
- `claude-haiku-4-5` - Near-frontier performance with the right speed and cost for high-volume use cases
|
||||
- `claude-opus-4-1` - Industry leader for coding, delivering sustained performance on long-running tasks
|
||||
|
||||
| Property | Details |
|
||||
|-------|-------|
|
||||
| Description | Claude models deployed via Microsoft Azure Foundry. Uses the same API as Anthropic's Messages API but with Azure authentication. |
|
||||
| Provider Route on LiteLLM | `azure_ai/` (add this prefix to Claude model names - e.g. `azure_ai/claude-sonnet-4-5`) |
|
||||
| Provider Doc | [Azure Foundry Claude Models ↗](https://learn.microsoft.com/en-us/azure/ai-services/foundry-models/claude) |
|
||||
| API Endpoint | `https://<resource-name>.services.ai.azure.com/anthropic/v1/messages` |
|
||||
| Supported Endpoints | `/chat/completions`, `/anthropic/v1/messages`|
|
||||
|
||||
## Key Features
|
||||
|
||||
- **Extended thinking**: Enhanced reasoning capabilities for complex tasks
|
||||
- **Image and text input**: Strong vision capabilities for analyzing charts, graphs, technical diagrams, and reports
|
||||
- **Code generation**: Advanced thinking with code generation, analysis, and debugging (Claude Sonnet 4.5 and Claude Opus 4.1)
|
||||
- **Same API as Anthropic**: All request/response transformations are identical to the main Anthropic provider
|
||||
|
||||
## Authentication
|
||||
|
||||
Azure Anthropic supports two authentication methods:
|
||||
|
||||
1. **API Key**: Use the `api-key` header
|
||||
2. **Azure AD Token**: Use `Authorization: Bearer <token>` header (Microsoft Entra ID)
|
||||
|
||||
## API Keys and Configuration
|
||||
|
||||
```python
|
||||
import os
|
||||
|
||||
# Option 1: API Key authentication
|
||||
os.environ["AZURE_API_KEY"] = "your-azure-api-key"
|
||||
os.environ["AZURE_API_BASE"] = "https://<resource-name>.services.ai.azure.com/anthropic"
|
||||
|
||||
# Option 2: Azure AD Token authentication
|
||||
os.environ["AZURE_AD_TOKEN"] = "your-azure-ad-token"
|
||||
os.environ["AZURE_API_BASE"] = "https://<resource-name>.services.ai.azure.com/anthropic"
|
||||
|
||||
# Optional: Azure AD Token Provider (for automatic token refresh)
|
||||
os.environ["AZURE_TENANT_ID"] = "your-tenant-id"
|
||||
os.environ["AZURE_CLIENT_ID"] = "your-client-id"
|
||||
os.environ["AZURE_CLIENT_SECRET"] = "your-client-secret"
|
||||
os.environ["AZURE_SCOPE"] = "https://cognitiveservices.azure.com/.default"
|
||||
```
|
||||
|
||||
## Usage - LiteLLM Python SDK
|
||||
|
||||
### Basic Completion
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
# Set environment variables
|
||||
os.environ["AZURE_API_KEY"] = "your-azure-api-key"
|
||||
os.environ["AZURE_API_BASE"] = "https://<resource-name>.services.ai.azure.com/anthropic"
|
||||
|
||||
# Make a completion request
|
||||
response = completion(
|
||||
model="azure_ai/claude-sonnet-4-5",
|
||||
messages=[
|
||||
{"role": "user", "content": "What are 3 things to visit in Seattle?"}
|
||||
],
|
||||
max_tokens=1000,
|
||||
temperature=0.7,
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
### Completion with API Key Parameter
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="azure_ai/claude-sonnet-4-5",
|
||||
api_base="https://<resource-name>.services.ai.azure.com/anthropic",
|
||||
api_key="your-azure-api-key",
|
||||
messages=[
|
||||
{"role": "user", "content": "Hello!"}
|
||||
],
|
||||
max_tokens=1000,
|
||||
)
|
||||
```
|
||||
|
||||
### Completion with Azure AD Token
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="azure_ai/claude-sonnet-4-5",
|
||||
api_base="https://<resource-name>.services.ai.azure.com/anthropic",
|
||||
azure_ad_token="your-azure-ad-token",
|
||||
messages=[
|
||||
{"role": "user", "content": "Hello!"}
|
||||
],
|
||||
max_tokens=1000,
|
||||
)
|
||||
```
|
||||
|
||||
### Streaming
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="azure_ai/claude-sonnet-4-5",
|
||||
messages=[
|
||||
{"role": "user", "content": "Write a short story"}
|
||||
],
|
||||
stream=True,
|
||||
max_tokens=1000,
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
if chunk.choices[0].delta.content:
|
||||
print(chunk.choices[0].delta.content, end="", flush=True)
|
||||
```
|
||||
|
||||
### Tool Calling
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="azure_ai/claude-sonnet-4-5",
|
||||
messages=[
|
||||
{"role": "user", "content": "What's the weather in Seattle?"}
|
||||
],
|
||||
tools=[
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get the current weather in a given location",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {
|
||||
"type": "string",
|
||||
"description": "The city and state, e.g. San Francisco, CA"
|
||||
}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
}
|
||||
}
|
||||
],
|
||||
tool_choice="auto",
|
||||
max_tokens=1000,
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
## Usage - LiteLLM Proxy Server
|
||||
|
||||
### 1. Save key in your environment
|
||||
|
||||
```bash
|
||||
export AZURE_API_KEY="your-azure-api-key"
|
||||
export AZURE_API_BASE="https://<resource-name>.services.ai.azure.com/anthropic"
|
||||
```
|
||||
|
||||
### 2. Configure the proxy
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-sonnet-4-5
|
||||
litellm_params:
|
||||
model: azure_ai/claude-sonnet-4-5
|
||||
api_base: https://<resource-name>.services.ai.azure.com/anthropic
|
||||
api_key: os.environ/AZURE_API_KEY
|
||||
```
|
||||
|
||||
### 3. Test it
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="curl" label="curl">
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "claude-sonnet-4-5",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Hello!"
|
||||
}
|
||||
],
|
||||
"max_tokens": 1000
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="openai" label="OpenAI Python SDK">
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
api_key="anything",
|
||||
base_url="http://0.0.0.0:4000"
|
||||
)
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="claude-sonnet-4-5",
|
||||
messages=[
|
||||
{"role": "user", "content": "Hello!"}
|
||||
],
|
||||
max_tokens=1000
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Messages API
|
||||
|
||||
Azure Anthropic also supports the native Anthropic Messages API. The endpoint structure is the same as Anthropic's `/v1/messages` API.
|
||||
|
||||
### Using Anthropic SDK
|
||||
|
||||
```python
|
||||
from anthropic import Anthropic
|
||||
|
||||
client = Anthropic(
|
||||
api_key="your-azure-api-key",
|
||||
base_url="https://<resource-name>.services.ai.azure.com/anthropic"
|
||||
)
|
||||
|
||||
response = client.messages.create(
|
||||
model="claude-sonnet-4-5",
|
||||
max_tokens=1000,
|
||||
messages=[
|
||||
{"role": "user", "content": "Hello, world"}
|
||||
]
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
### Using LiteLLM Proxy
|
||||
|
||||
```bash
|
||||
curl --request POST \
|
||||
--url http://0.0.0.0:4000/anthropic/v1/messages \
|
||||
--header 'accept: application/json' \
|
||||
--header 'content-type: application/json' \
|
||||
--header "Authorization: bearer sk-anything" \
|
||||
--data '{
|
||||
"model": "claude-sonnet-4-5",
|
||||
"max_tokens": 1024,
|
||||
"messages": [
|
||||
{"role": "user", "content": "Hello, world"}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
## Supported OpenAI Parameters
|
||||
|
||||
Azure Anthropic supports the same parameters as the main Anthropic provider:
|
||||
|
||||
```
|
||||
"stream",
|
||||
"stop",
|
||||
"temperature",
|
||||
"top_p",
|
||||
"max_tokens",
|
||||
"max_completion_tokens",
|
||||
"tools",
|
||||
"tool_choice",
|
||||
"extra_headers",
|
||||
"parallel_tool_calls",
|
||||
"response_format",
|
||||
"user",
|
||||
"thinking",
|
||||
"reasoning_effort"
|
||||
```
|
||||
|
||||
:::info
|
||||
|
||||
Azure Anthropic API requires `max_tokens` to be passed. LiteLLM automatically passes `max_tokens=4096` when no `max_tokens` are provided.
|
||||
|
||||
:::
|
||||
|
||||
## Differences from Standard Anthropic Provider
|
||||
|
||||
The only difference between Azure Anthropic and the standard Anthropic provider is authentication:
|
||||
|
||||
- **Standard Anthropic**: Uses `x-api-key` header
|
||||
- **Azure Anthropic**: Uses `api-key` header or `Authorization: Bearer <token>` for Azure AD authentication
|
||||
|
||||
All other request/response transformations, tool calling, streaming, and feature support are identical.
|
||||
|
||||
## API Base URL Format
|
||||
|
||||
The API base URL should follow this format:
|
||||
|
||||
```
|
||||
https://<resource-name>.services.ai.azure.com/anthropic
|
||||
```
|
||||
|
||||
LiteLLM will automatically append `/v1/messages` if not already present in the URL.
|
||||
|
||||
## Example: Full Configuration
|
||||
|
||||
```python
|
||||
import os
|
||||
from litellm import completion
|
||||
|
||||
# Configure Azure Anthropic
|
||||
os.environ["AZURE_API_KEY"] = "your-azure-api-key"
|
||||
os.environ["AZURE_API_BASE"] = "https://my-resource.services.ai.azure.com/anthropic"
|
||||
|
||||
# Make a request
|
||||
response = completion(
|
||||
model="azure_ai/claude-sonnet-4-5",
|
||||
messages=[
|
||||
{"role": "system", "content": "You are a helpful assistant."},
|
||||
{"role": "user", "content": "Explain quantum computing in simple terms."}
|
||||
],
|
||||
max_tokens=1000,
|
||||
temperature=0.7,
|
||||
stream=False,
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
### Missing API Base Error
|
||||
|
||||
If you see an error about missing API base, ensure you've set:
|
||||
|
||||
```python
|
||||
os.environ["AZURE_API_BASE"] = "https://<resource-name>.services.ai.azure.com/anthropic"
|
||||
```
|
||||
|
||||
Or pass it directly:
|
||||
|
||||
```python
|
||||
response = completion(
|
||||
model="azure_ai/claude-sonnet-4-5",
|
||||
api_base="https://<resource-name>.services.ai.azure.com/anthropic",
|
||||
# ...
|
||||
)
|
||||
```
|
||||
|
||||
### Authentication Errors
|
||||
|
||||
- **API Key**: Ensure `AZURE_API_KEY` is set or passed as `api_key` parameter
|
||||
- **Azure AD Token**: Ensure `AZURE_AD_TOKEN` is set or passed as `azure_ad_token` parameter
|
||||
- **Token Provider**: For automatic token refresh, configure `AZURE_TENANT_ID`, `AZURE_CLIENT_ID`, and `AZURE_CLIENT_SECRET`
|
||||
|
||||
## Related Documentation
|
||||
|
||||
- [Anthropic Provider Documentation](./anthropic.md) - For standard Anthropic API usage
|
||||
- [Azure OpenAI Documentation](./azure.md) - For Azure OpenAI models
|
||||
- [Azure Authentication Guide](../secret_managers/azure_key_vault.md) - For Azure AD token setup
|
||||
|
||||
|
|
@ -312,6 +312,82 @@ LiteLLM supports **ALL** azure ai models. Here's a few examples:
|
|||
| mistral-large-latest | `completion(model="azure_ai/mistral-large-latest", messages)` |
|
||||
| AI21-Jamba-Instruct | `completion(model="azure_ai/ai21-jamba-instruct", messages)` |
|
||||
|
||||
## Usage - Azure Anthropic (Azure Foundry Claude)
|
||||
|
||||
LiteLLM funnels Azure Claude deployments through the `azure_ai/` provider so Claude Opus models on Azure Foundry keep working with Tool Search, Effort, streaming, and the rest of the advanced feature set. Point `AZURE_AI_API_BASE` to `https://<resource>.services.ai.azure.com/anthropic` (LiteLLM appends `/v1/messages` automatically) and authenticate with `AZURE_AI_API_KEY` or an Azure AD token.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="LiteLLM Python SDK">
|
||||
|
||||
```python
|
||||
import os
|
||||
from litellm import completion
|
||||
|
||||
# Configure Azure credentials
|
||||
os.environ["AZURE_AI_API_KEY"] = "your-azure-ai-api-key"
|
||||
os.environ["AZURE_AI_API_BASE"] = "https://my-resource.services.ai.azure.com/anthropic"
|
||||
|
||||
response = completion(
|
||||
model="azure_ai/claude-opus-4-1",
|
||||
messages=[{"role": "user", "content": "Explain how Azure Anthropic hosts Claude Opus differently from the public Anthropic API."}],
|
||||
max_tokens=1200,
|
||||
temperature=0.7,
|
||||
stream=True,
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
if chunk.choices[0].delta.content:
|
||||
print(chunk.choices[0].delta.content, end="", flush=True)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Set environment variables**
|
||||
|
||||
```bash
|
||||
export AZURE_AI_API_KEY="your-azure-ai-api-key"
|
||||
export AZURE_AI_API_BASE="https://my-resource.services.ai.azure.com/anthropic"
|
||||
```
|
||||
|
||||
**2. Configure the proxy**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-4-azure
|
||||
litellm_params:
|
||||
model: azure_ai/claude-opus-4-1
|
||||
api_key: os.environ/AZURE_AI_API_KEY
|
||||
api_base: os.environ/AZURE_AI_API_BASE
|
||||
```
|
||||
|
||||
**3. Start LiteLLM**
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
**4. Test the Azure Claude route**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-4-azure",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "How do I use Claude Opus 4 via Azure Anthropic in LiteLLM?"
|
||||
}
|
||||
],
|
||||
"max_tokens": 1024
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
||||
|
||||
## Rerank Endpoint
|
||||
|
|
@ -397,4 +473,5 @@ curl http://0.0.0.0:4000/rerank \
|
|||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
</Tabs>
|
||||
|
||||
|
|
|
|||
334
docs/my-website/docs/providers/azure_ai_agents.md
Normal file
334
docs/my-website/docs/providers/azure_ai_agents.md
Normal file
|
|
@ -0,0 +1,334 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Azure AI Foundry Agents
|
||||
|
||||
Call Azure AI Foundry Agents in the OpenAI Request/Response format.
|
||||
|
||||
| Property | Details |
|
||||
|----------|---------|
|
||||
| Description | Azure AI Foundry Agents provides hosted agent runtimes that can execute agentic workflows with foundation models, tools, and code interpreters. |
|
||||
| Provider Route on LiteLLM | `azure_ai/agents/{AGENT_ID}` |
|
||||
| Provider Doc | [Azure AI Foundry Agents ↗](https://learn.microsoft.com/en-us/azure/ai-foundry/agents/quickstart) |
|
||||
|
||||
## Authentication
|
||||
|
||||
Azure AI Foundry Agents require **Azure AD authentication** (not API keys). You can authenticate using:
|
||||
|
||||
### Option 1: Service Principal (Recommended for Production)
|
||||
|
||||
Set these environment variables:
|
||||
|
||||
```bash
|
||||
export AZURE_TENANT_ID="your-tenant-id"
|
||||
export AZURE_CLIENT_ID="your-client-id"
|
||||
export AZURE_CLIENT_SECRET="your-client-secret"
|
||||
```
|
||||
|
||||
LiteLLM will automatically obtain an Azure AD token using these credentials.
|
||||
|
||||
### Option 2: Azure AD Token (Manual)
|
||||
|
||||
Pass a token directly via `api_key`:
|
||||
|
||||
```bash
|
||||
# Get token via Azure CLI
|
||||
az account get-access-token --resource "https://ai.azure.com" --query accessToken -o tsv
|
||||
```
|
||||
|
||||
### Required Azure Role
|
||||
|
||||
Your Service Principal or user must have the **Azure AI Developer** or **Azure AI User** role on your Azure AI Foundry project.
|
||||
|
||||
To assign via Azure CLI:
|
||||
```bash
|
||||
az role assignment create \
|
||||
--assignee-object-id "<service-principal-object-id>" \
|
||||
--assignee-principal-type "ServicePrincipal" \
|
||||
--role "Azure AI Developer" \
|
||||
--scope "/subscriptions/<sub>/resourceGroups/<rg>/providers/Microsoft.CognitiveServices/accounts/<resource>"
|
||||
```
|
||||
|
||||
Or add via **Azure AI Foundry Portal** → Your Project → **Project users** → **+ New user**.
|
||||
|
||||
## Quick Start
|
||||
|
||||
### Model Format to LiteLLM
|
||||
|
||||
To call an Azure AI Foundry Agent through LiteLLM, use the following model format.
|
||||
|
||||
Here the `model=azure_ai/agents/` tells LiteLLM to call the Azure AI Foundry Agent Service API.
|
||||
|
||||
```shell showLineNumbers title="Model Format to LiteLLM"
|
||||
azure_ai/agents/{AGENT_ID}
|
||||
```
|
||||
|
||||
**Example:**
|
||||
- `azure_ai/agents/asst_abc123`
|
||||
|
||||
You can find the Agent ID in your Azure AI Foundry portal under Agents.
|
||||
|
||||
### LiteLLM Python SDK
|
||||
|
||||
```python showLineNumbers title="Basic Agent Completion"
|
||||
import litellm
|
||||
|
||||
# Make a completion request to your Azure AI Foundry Agent
|
||||
# Uses AZURE_TENANT_ID, AZURE_CLIENT_ID, AZURE_CLIENT_SECRET env vars for auth
|
||||
response = litellm.completion(
|
||||
model="azure_ai/agents/asst_abc123",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Explain machine learning in simple terms"
|
||||
}
|
||||
],
|
||||
api_base="https://your-resource.services.ai.azure.com/api/projects/your-project",
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
print(f"Usage: {response.usage}")
|
||||
```
|
||||
|
||||
```python showLineNumbers title="Streaming Agent Responses"
|
||||
import litellm
|
||||
|
||||
# Stream responses from your Azure AI Foundry Agent
|
||||
response = await litellm.acompletion(
|
||||
model="azure_ai/agents/asst_abc123",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What are the key principles of software architecture?"
|
||||
}
|
||||
],
|
||||
api_base="https://your-resource.services.ai.azure.com/api/projects/your-project",
|
||||
stream=True,
|
||||
)
|
||||
|
||||
async for chunk in response:
|
||||
if chunk.choices[0].delta.content:
|
||||
print(chunk.choices[0].delta.content, end="")
|
||||
```
|
||||
|
||||
### LiteLLM Proxy
|
||||
|
||||
#### 1. Configure your model in config.yaml
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="config-yaml" label="config.yaml">
|
||||
|
||||
```yaml showLineNumbers title="LiteLLM Proxy Configuration"
|
||||
model_list:
|
||||
- model_name: azure-agent-1
|
||||
litellm_params:
|
||||
model: azure_ai/agents/asst_abc123
|
||||
api_base: https://your-resource.services.ai.azure.com/api/projects/your-project
|
||||
# Service Principal auth (recommended)
|
||||
tenant_id: os.environ/AZURE_TENANT_ID
|
||||
client_id: os.environ/AZURE_CLIENT_ID
|
||||
client_secret: os.environ/AZURE_CLIENT_SECRET
|
||||
|
||||
- model_name: azure-agent-math-tutor
|
||||
litellm_params:
|
||||
model: azure_ai/agents/asst_def456
|
||||
api_base: https://your-resource.services.ai.azure.com/api/projects/your-project
|
||||
# Or pass Azure AD token directly
|
||||
api_key: os.environ/AZURE_AD_TOKEN
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
#### 2. Start the LiteLLM Proxy
|
||||
|
||||
```bash showLineNumbers title="Start LiteLLM Proxy"
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
#### 3. Make requests to your Azure AI Foundry Agents
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="curl" label="Curl">
|
||||
|
||||
```bash showLineNumbers title="Basic Agent Request"
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer $LITELLM_API_KEY" \
|
||||
-d '{
|
||||
"model": "azure-agent-1",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Summarize the main benefits of cloud computing"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
```bash showLineNumbers title="Streaming Agent Request"
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer $LITELLM_API_KEY" \
|
||||
-d '{
|
||||
"model": "azure-agent-math-tutor",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What is 25 * 4?"
|
||||
}
|
||||
],
|
||||
"stream": true
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="openai-sdk" label="OpenAI Python SDK">
|
||||
|
||||
```python showLineNumbers title="Using OpenAI SDK with LiteLLM Proxy"
|
||||
from openai import OpenAI
|
||||
|
||||
# Initialize client with your LiteLLM proxy URL
|
||||
client = OpenAI(
|
||||
base_url="http://localhost:4000",
|
||||
api_key="your-litellm-api-key"
|
||||
)
|
||||
|
||||
# Make a completion request to your Azure AI Foundry Agent
|
||||
response = client.chat.completions.create(
|
||||
model="azure-agent-1",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What are best practices for API design?"
|
||||
}
|
||||
]
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
```python showLineNumbers title="Streaming with OpenAI SDK"
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
base_url="http://localhost:4000",
|
||||
api_key="your-litellm-api-key"
|
||||
)
|
||||
|
||||
# Stream Agent responses
|
||||
stream = client.chat.completions.create(
|
||||
model="azure-agent-math-tutor",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Explain the Pythagorean theorem"
|
||||
}
|
||||
],
|
||||
stream=True
|
||||
)
|
||||
|
||||
for chunk in stream:
|
||||
if chunk.choices[0].delta.content is not None:
|
||||
print(chunk.choices[0].delta.content, end="")
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Environment Variables
|
||||
|
||||
| Variable | Description |
|
||||
|----------|-------------|
|
||||
| `AZURE_TENANT_ID` | Azure AD tenant ID for Service Principal auth |
|
||||
| `AZURE_CLIENT_ID` | Application (client) ID of your Service Principal |
|
||||
| `AZURE_CLIENT_SECRET` | Client secret for your Service Principal |
|
||||
|
||||
```bash
|
||||
export AZURE_TENANT_ID="your-tenant-id"
|
||||
export AZURE_CLIENT_ID="your-client-id"
|
||||
export AZURE_CLIENT_SECRET="your-client-secret"
|
||||
```
|
||||
|
||||
## Conversation Continuity (Thread Management)
|
||||
|
||||
Azure AI Foundry Agents use threads to maintain conversation context. LiteLLM automatically manages threads for you, but you can also pass an existing thread ID to continue a conversation.
|
||||
|
||||
```python showLineNumbers title="Continuing a Conversation"
|
||||
import litellm
|
||||
|
||||
# First message creates a new thread
|
||||
response1 = await litellm.acompletion(
|
||||
model="azure_ai/agents/asst_abc123",
|
||||
messages=[{"role": "user", "content": "My name is Alice"}],
|
||||
api_base="https://your-resource.services.ai.azure.com/api/projects/your-project",
|
||||
)
|
||||
|
||||
# Get the thread_id from the response
|
||||
thread_id = response1._hidden_params.get("thread_id")
|
||||
|
||||
# Continue the conversation using the same thread
|
||||
response2 = await litellm.acompletion(
|
||||
model="azure_ai/agents/asst_abc123",
|
||||
messages=[{"role": "user", "content": "What's my name?"}],
|
||||
api_base="https://your-resource.services.ai.azure.com/api/projects/your-project",
|
||||
thread_id=thread_id, # Pass the thread_id to continue conversation
|
||||
)
|
||||
|
||||
print(response2.choices[0].message.content) # Should mention "Alice"
|
||||
```
|
||||
|
||||
## Provider-specific Parameters
|
||||
|
||||
Azure AI Foundry Agents support additional parameters that can be passed to customize the agent invocation.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python showLineNumbers title="Using Agent-specific parameters"
|
||||
from litellm import completion
|
||||
|
||||
response = litellm.completion(
|
||||
model="azure_ai/agents/asst_abc123",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Analyze this data and provide insights",
|
||||
}
|
||||
],
|
||||
api_base="https://your-resource.services.ai.azure.com/api/projects/your-project",
|
||||
thread_id="thread_abc123", # Optional: Continue existing conversation
|
||||
instructions="Be concise and focus on key insights", # Optional: Override agent instructions
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="Proxy">
|
||||
|
||||
```yaml showLineNumbers title="LiteLLM Proxy Configuration with Parameters"
|
||||
model_list:
|
||||
- model_name: azure-agent-analyst
|
||||
litellm_params:
|
||||
model: azure_ai/agents/asst_abc123
|
||||
api_base: https://your-resource.services.ai.azure.com/api/projects/your-project
|
||||
tenant_id: os.environ/AZURE_TENANT_ID
|
||||
client_id: os.environ/AZURE_CLIENT_ID
|
||||
client_secret: os.environ/AZURE_CLIENT_SECRET
|
||||
instructions: "Be concise and focus on key insights"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Available Parameters
|
||||
|
||||
| Parameter | Type | Description |
|
||||
|-----------|------|-------------|
|
||||
| `thread_id` | string | Optional thread ID to continue an existing conversation |
|
||||
| `instructions` | string | Optional instructions to override the agent's default instructions for this run |
|
||||
|
||||
## Further Reading
|
||||
|
||||
- [Azure AI Foundry Agents Documentation](https://learn.microsoft.com/en-us/azure/ai-services/agents/)
|
||||
- [Create Thread and Run API Reference](https://learn.microsoft.com/en-us/rest/api/aifoundry/aiagents/create-thread-and-run/create-thread-and-run)
|
||||
|
|
@ -136,6 +136,89 @@ response = speech(
|
|||
| `wav` | riff-24khz-16bit-mono-pcm | 24kHz |
|
||||
| `pcm` | raw-24khz-16bit-mono-pcm | 24kHz |
|
||||
|
||||
## Passing Raw SSML
|
||||
|
||||
LiteLLM automatically detects when your `input` contains SSML (by checking for `<speak>` tags) and passes it through to Azure without any transformation. This gives you complete control over speech synthesis.
|
||||
|
||||
**When to use raw SSML:**
|
||||
- Using the `<lang>` element with multilingual voices to translate text (e.g., English text → Spanish speech)
|
||||
- Complex SSML structures with multiple voices or prosody changes
|
||||
- Fine-grained control over pronunciation, breaks, emphasis, and other speech features
|
||||
|
||||
### LiteLLM SDK
|
||||
|
||||
```python showLineNumbers title="Raw SSML for Multilingual Translation"
|
||||
from litellm import speech
|
||||
|
||||
# Use <lang> element to convert English text to Spanish speech
|
||||
# The <lang> element forces the output language regardless of input text language
|
||||
language_code = "es-ES"
|
||||
text = "Hello, how are you today?" # English text
|
||||
voice = "en-US-AvaMultilingualNeural"
|
||||
|
||||
ssml = f"""<speak version="1.0"
|
||||
xmlns="http://www.w3.org/2001/10/synthesis"
|
||||
xmlns:mstts="http://www.w3.org/2001/mstts"
|
||||
xml:lang="{language_code}">
|
||||
<voice name="{voice}">
|
||||
<lang xml:lang="{language_code}">{text}</lang>
|
||||
</voice>
|
||||
</speak>"""
|
||||
|
||||
response = speech(
|
||||
model="azure/speech/azure-tts",
|
||||
voice=voice,
|
||||
input=ssml, # LiteLLM auto-detects SSML and sends as-is
|
||||
api_base="https://eastus.tts.speech.microsoft.com",
|
||||
api_key=os.environ["AZURE_TTS_API_KEY"],
|
||||
)
|
||||
response.stream_to_file("speech.mp3")
|
||||
```
|
||||
|
||||
```python showLineNumbers title="Raw SSML with Complex Features"
|
||||
from litellm import speech
|
||||
|
||||
# Complex SSML with multiple prosody adjustments
|
||||
ssml = """<speak version='1.0' xmlns='http://www.w3.org/2001/10/synthesis'
|
||||
xmlns:mstts='https://www.w3.org/2001/mstts' xml:lang='en-US'>
|
||||
<voice name='en-US-JennyNeural'>
|
||||
<mstts:express-as style='cheerful' styledegree='2'>
|
||||
<prosody rate='+20%' pitch='high'>
|
||||
Welcome to our service!
|
||||
</prosody>
|
||||
</mstts:express-as>
|
||||
<break time='500ms'/>
|
||||
<prosody rate='-10%'>
|
||||
How can I help you today?
|
||||
</prosody>
|
||||
</voice>
|
||||
</speak>"""
|
||||
|
||||
response = speech(
|
||||
model="azure/speech/azure-tts",
|
||||
voice="en-US-JennyNeural",
|
||||
input=ssml, # LiteLLM detects <speak> and passes through unchanged
|
||||
api_base="https://eastus.tts.speech.microsoft.com",
|
||||
api_key=os.environ["AZURE_TTS_API_KEY"],
|
||||
)
|
||||
response.stream_to_file("speech.mp3")
|
||||
```
|
||||
|
||||
### LiteLLM Proxy
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/audio/speech \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "azure-speech",
|
||||
"voice": "en-US-AvaMultilingualNeural",
|
||||
"input": "<speak version=\"1.0\" xmlns=\"http://www.w3.org/2001/10/synthesis\" xmlns:mstts=\"http://www.w3.org/2001/mstts\" xml:lang=\"es-ES\"><voice name=\"en-US-AvaMultilingualNeural\"><lang xml:lang=\"es-ES\">Hello, how are you today?</lang></voice></speak>"
|
||||
}' \
|
||||
--output speech.mp3
|
||||
```
|
||||
|
||||
|
||||
## Sending Azure-Specific Params
|
||||
|
||||
Azure AI Speech supports advanced SSML features through optional parameters:
|
||||
|
|
|
|||
|
|
@ -7,7 +7,7 @@ ALL Bedrock models (Anthropic, Meta, Deepseek, Mistral, Amazon, etc.) are Suppor
|
|||
| Property | Details |
|
||||
|-------|-------|
|
||||
| Description | Amazon Bedrock is a fully managed service that offers a choice of high-performing foundation models (FMs). |
|
||||
| Provider Route on LiteLLM | `bedrock/`, [`bedrock/converse/`](#set-converse--invoke-route), [`bedrock/invoke/`](#set-invoke-route), [`bedrock/converse_like/`](#calling-via-internal-proxy), [`bedrock/llama/`](#deepseek-not-r1), [`bedrock/deepseek_r1/`](#deepseek-r1), [`bedrock/qwen3/`](#qwen3-imported-models) |
|
||||
| Provider Route on LiteLLM | `bedrock/`, [`bedrock/converse/`](#set-converse--invoke-route), [`bedrock/invoke/`](#set-invoke-route), [`bedrock/converse_like/`](#calling-via-internal-proxy), [`bedrock/llama/`](#deepseek-not-r1), [`bedrock/deepseek_r1/`](#deepseek-r1), [`bedrock/qwen3/`](#qwen3-imported-models), [`bedrock/qwen2/`](./bedrock_imported.md#qwen2-imported-models), [`bedrock/openai/`](./bedrock_imported.md#openai-compatible-imported-models-qwen-25-vl-etc) |
|
||||
| Provider Doc | [Amazon Bedrock ↗](https://docs.aws.amazon.com/bedrock/latest/userguide/what-is-bedrock.html) |
|
||||
| Supported OpenAI Endpoints | `/chat/completions`, `/completions`, `/embeddings`, `/images/generations` |
|
||||
| Rerank Endpoint | `/rerank` |
|
||||
|
|
@ -43,6 +43,8 @@ export AWS_BEARER_TOKEN_BEDROCK="your-api-key"
|
|||
|
||||
Option 2: use the api_key parameter to pass in API key for completion, embedding, image_generation API calls.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
```python
|
||||
response = completion(
|
||||
model="bedrock/anthropic.claude-3-sonnet-20240229-v1:0",
|
||||
|
|
@ -50,7 +52,17 @@ response = completion(
|
|||
api_key="your-api-key"
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: bedrock-claude-3-sonnet
|
||||
litellm_params:
|
||||
model: bedrock/anthropic.claude-3-sonnet-20240229-v1:0
|
||||
api_key: os.environ/AWS_BEARER_TOKEN_BEDROCK
|
||||
```
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage
|
||||
|
||||
|
|
@ -945,6 +957,65 @@ curl http://0.0.0.0:4000/v1/chat/completions \
|
|||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Service Tier
|
||||
|
||||
Control the processing tier for your Bedrock requests using `serviceTier`. Valid values are `priority`, `default`, or `flex`.
|
||||
|
||||
- `priority`: Higher priority processing with guaranteed capacity
|
||||
- `default`: Standard processing tier
|
||||
- `flex`: Cost-optimized processing for batch workloads
|
||||
|
||||
[Bedrock ServiceTier API Reference](https://docs.aws.amazon.com/bedrock/latest/APIReference/API_runtime_ServiceTier.html)
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="bedrock/converse/qwen.qwen3-235b-a22b-2507-v1:0",
|
||||
messages=[{"role": "user", "content": "What is the capital of France?"}],
|
||||
serviceTier={"type": "priority"},
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
1. Setup config.yaml
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: qwen3-235b-priority
|
||||
litellm_params:
|
||||
model: bedrock/converse/qwen.qwen3-235b-a22b-2507-v1:0
|
||||
aws_region_name: ap-northeast-1
|
||||
serviceTier:
|
||||
type: priority
|
||||
```
|
||||
|
||||
2. Start proxy
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
3. Test it!
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer $LITELLM_KEY" \
|
||||
-d '{
|
||||
"model": "qwen3-235b-priority",
|
||||
"messages": [{"role": "user", "content": "What is the capital of France?"}],
|
||||
"serviceTier": {"type": "priority"}
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
## Usage - Bedrock Guardrails
|
||||
|
||||
Example of using [Bedrock Guardrails with LiteLLM](https://docs.aws.amazon.com/bedrock/latest/userguide/guardrails-use-converse-api.html)
|
||||
|
|
@ -1598,206 +1669,6 @@ curl -X POST 'http://0.0.0.0:4000/chat/completions' \
|
|||
</Tabs>
|
||||
|
||||
|
||||
## Bedrock Imported Models (Deepseek, Deepseek R1)
|
||||
|
||||
### Deepseek R1
|
||||
|
||||
This is a separate route, as the chat template is different.
|
||||
|
||||
| Property | Details |
|
||||
|----------|---------|
|
||||
| Provider Route | `bedrock/deepseek_r1/{model_arn}` |
|
||||
| Provider Documentation | [Bedrock Imported Models](https://docs.aws.amazon.com/bedrock/latest/userguide/model-customization-import-model.html), [Deepseek Bedrock Imported Model](https://aws.amazon.com/blogs/machine-learning/deploy-deepseek-r1-distilled-llama-models-with-amazon-bedrock-custom-model-import/) |
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
import os
|
||||
|
||||
response = completion(
|
||||
model="bedrock/deepseek_r1/arn:aws:bedrock:us-east-1:086734376398:imported-model/r4c4kewx2s0n", # bedrock/deepseek_r1/{your-model-arn}
|
||||
messages=[{"role": "user", "content": "Tell me a joke"}],
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="proxy" label="Proxy">
|
||||
|
||||
|
||||
**1. Add to config**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: DeepSeek-R1-Distill-Llama-70B
|
||||
litellm_params:
|
||||
model: bedrock/deepseek_r1/arn:aws:bedrock:us-east-1:086734376398:imported-model/r4c4kewx2s0n
|
||||
|
||||
```
|
||||
|
||||
**2. Start proxy**
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING at http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Authorization: Bearer sk-1234' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "DeepSeek-R1-Distill-Llama-70B", # 👈 the 'model_name' in config
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
||||
### Deepseek (not R1)
|
||||
|
||||
| Property | Details |
|
||||
|----------|---------|
|
||||
| Provider Route | `bedrock/llama/{model_arn}` |
|
||||
| Provider Documentation | [Bedrock Imported Models](https://docs.aws.amazon.com/bedrock/latest/userguide/model-customization-import-model.html), [Deepseek Bedrock Imported Model](https://aws.amazon.com/blogs/machine-learning/deploy-deepseek-r1-distilled-llama-models-with-amazon-bedrock-custom-model-import/) |
|
||||
|
||||
|
||||
|
||||
Use this route to call Bedrock Imported Models that follow the `llama` Invoke Request / Response spec
|
||||
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
import os
|
||||
|
||||
response = completion(
|
||||
model="bedrock/llama/arn:aws:bedrock:us-east-1:086734376398:imported-model/r4c4kewx2s0n", # bedrock/llama/{your-model-arn}
|
||||
messages=[{"role": "user", "content": "Tell me a joke"}],
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="proxy" label="Proxy">
|
||||
|
||||
|
||||
**1. Add to config**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: DeepSeek-R1-Distill-Llama-70B
|
||||
litellm_params:
|
||||
model: bedrock/llama/arn:aws:bedrock:us-east-1:086734376398:imported-model/r4c4kewx2s0n
|
||||
|
||||
```
|
||||
|
||||
**2. Start proxy**
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING at http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Authorization: Bearer sk-1234' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "DeepSeek-R1-Distill-Llama-70B", # 👈 the 'model_name' in config
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Qwen3 Imported Models
|
||||
|
||||
| Property | Details |
|
||||
|----------|---------|
|
||||
| Provider Route | `bedrock/qwen3/{model_arn}` |
|
||||
| Provider Documentation | [Bedrock Imported Models](https://docs.aws.amazon.com/bedrock/latest/userguide/model-customization-import-model.html), [Qwen3 Models](https://aws.amazon.com/about-aws/whats-new/2025/09/qwen3-models-fully-managed-amazon-bedrock/) |
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
import os
|
||||
|
||||
response = completion(
|
||||
model="bedrock/qwen3/arn:aws:bedrock:us-east-1:086734376398:imported-model/your-qwen3-model", # bedrock/qwen3/{your-model-arn}
|
||||
messages=[{"role": "user", "content": "Tell me a joke"}],
|
||||
max_tokens=100,
|
||||
temperature=0.7
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="proxy" label="Proxy">
|
||||
|
||||
**1. Add to config**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: Qwen3-32B
|
||||
litellm_params:
|
||||
model: bedrock/qwen3/arn:aws:bedrock:us-east-1:086734376398:imported-model/your-qwen3-model
|
||||
|
||||
```
|
||||
|
||||
**2. Start proxy**
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING at http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Authorization: Bearer sk-1234' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "Qwen3-32B", # 👈 the 'model_name' in config
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### OpenAI GPT OSS
|
||||
|
||||
| Property | Details |
|
||||
|
|
@ -1883,6 +1754,131 @@ curl --location 'http://0.0.0.0:4000/chat/completions' \
|
|||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## TwelveLabs Pegasus - Video Understanding
|
||||
|
||||
TwelveLabs Pegasus 1.2 is a video understanding model that can analyze and describe video content. LiteLLM supports this model through Bedrock's `/invoke` endpoint.
|
||||
|
||||
| Property | Details |
|
||||
|----------|---------|
|
||||
| Provider Route | `bedrock/us.twelvelabs.pegasus-1-2-v1:0`, `bedrock/eu.twelvelabs.pegasus-1-2-v1:0` |
|
||||
| Provider Documentation | [TwelveLabs Pegasus Docs ↗](https://docs.twelvelabs.io/docs/models/pegasus) |
|
||||
| Supported Parameters | `max_tokens`, `temperature`, `response_format` |
|
||||
| Media Input | S3 URI or base64-encoded video |
|
||||
|
||||
### Supported Features
|
||||
|
||||
- **Video Analysis**: Analyze video content from S3 or base64 input
|
||||
- **Structured Output**: Support for JSON schema response format
|
||||
- **S3 Integration**: Support for S3 video URLs with bucket owner specification
|
||||
|
||||
### Usage with S3 Video
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python title="TwelveLabs Pegasus SDK Usage" showLineNumbers
|
||||
from litellm import completion
|
||||
import os
|
||||
|
||||
# Set AWS credentials
|
||||
os.environ["AWS_ACCESS_KEY_ID"] = "your-aws-access-key"
|
||||
os.environ["AWS_SECRET_ACCESS_KEY"] = "your-aws-secret-key"
|
||||
os.environ["AWS_REGION_NAME"] = "us-east-1"
|
||||
|
||||
response = completion(
|
||||
model="bedrock/us.twelvelabs.pegasus-1-2-v1:0",
|
||||
messages=[{"role": "user", "content": "Describe what happens in this video."}],
|
||||
mediaSource={
|
||||
"s3Location": {
|
||||
"uri": "s3://your-bucket/video.mp4",
|
||||
"bucketOwner": "123456789012", # 12-digit AWS account ID
|
||||
}
|
||||
},
|
||||
temperature=0.2
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="proxy" label="Proxy">
|
||||
|
||||
**1. Add to config**
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
model_list:
|
||||
- model_name: pegasus-video
|
||||
litellm_params:
|
||||
model: bedrock/us.twelvelabs.pegasus-1-2-v1:0
|
||||
aws_access_key_id: os.environ/AWS_ACCESS_KEY_ID
|
||||
aws_secret_access_key: os.environ/AWS_SECRET_ACCESS_KEY
|
||||
aws_region_name: os.environ/AWS_REGION_NAME
|
||||
```
|
||||
|
||||
**2. Start proxy**
|
||||
|
||||
```bash title="Start LiteLLM Proxy" showLineNumbers
|
||||
litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING at http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash title="Test Pegasus via Proxy" showLineNumbers
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Authorization: Bearer sk-1234' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "pegasus-video",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Describe what happens in this video."
|
||||
}
|
||||
],
|
||||
"mediaSource": {
|
||||
"s3Location": {
|
||||
"uri": "s3://your-bucket/video.mp4",
|
||||
"bucketOwner": "123456789012"
|
||||
}
|
||||
},
|
||||
"temperature": 0.2
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Usage with Base64 Video
|
||||
|
||||
You can also pass video content directly as base64:
|
||||
|
||||
```python title="Base64 Video Input" showLineNumbers
|
||||
from litellm import completion
|
||||
import base64
|
||||
|
||||
# Read video file and encode to base64
|
||||
with open("video.mp4", "rb") as video_file:
|
||||
video_base64 = base64.b64encode(video_file.read()).decode("utf-8")
|
||||
|
||||
response = completion(
|
||||
model="bedrock/us.twelvelabs.pegasus-1-2-v1:0",
|
||||
messages=[{"role": "user", "content": "What is happening in this video?"}],
|
||||
mediaSource={
|
||||
"base64String": video_base64
|
||||
},
|
||||
temperature=0.2,
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
### Important Notes
|
||||
|
||||
- **Response Format**: The model supports structured output via `response_format` with JSON schema
|
||||
|
||||
## Provisioned throughput models
|
||||
To use provisioned throughput Bedrock models pass
|
||||
- `model=bedrock/<base-model>`, example `model=bedrock/anthropic.claude-v2`. Set `model` to any of the [Supported AWS models](#supported-aws-bedrock-models)
|
||||
|
|
@ -1943,6 +1939,8 @@ Here's an example of using a bedrock model with LiteLLM. For a complete list, re
|
|||
| Meta Llama 2 Chat 70b | `completion(model='bedrock/meta.llama2-70b-chat-v1', messages=messages)` | `os.environ['AWS_ACCESS_KEY_ID']`, `os.environ['AWS_SECRET_ACCESS_KEY']`, `os.environ['AWS_REGION_NAME']` |
|
||||
| Mistral 7B Instruct | `completion(model='bedrock/mistral.mistral-7b-instruct-v0:2', messages=messages)` | `os.environ['AWS_ACCESS_KEY_ID']`, `os.environ['AWS_SECRET_ACCESS_KEY']`, `os.environ['AWS_REGION_NAME']` |
|
||||
| Mixtral 8x7B Instruct | `completion(model='bedrock/mistral.mixtral-8x7b-instruct-v0:1', messages=messages)` | `os.environ['AWS_ACCESS_KEY_ID']`, `os.environ['AWS_SECRET_ACCESS_KEY']`, `os.environ['AWS_REGION_NAME']` |
|
||||
| TwelveLabs Pegasus 1.2 (US) | `completion(model='bedrock/us.twelvelabs.pegasus-1-2-v1:0', messages=messages, mediaSource={...})` | `os.environ['AWS_ACCESS_KEY_ID']`, `os.environ['AWS_SECRET_ACCESS_KEY']`, `os.environ['AWS_REGION_NAME']` |
|
||||
| TwelveLabs Pegasus 1.2 (EU) | `completion(model='bedrock/eu.twelvelabs.pegasus-1-2-v1:0', messages=messages, mediaSource={...})` | `os.environ['AWS_ACCESS_KEY_ID']`, `os.environ['AWS_SECRET_ACCESS_KEY']`, `os.environ['AWS_REGION_NAME']` |
|
||||
|
||||
|
||||
## Bedrock Embedding
|
||||
|
|
|
|||
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue