mirror of
https://github.com/BerriAI/litellm.git
synced 2026-10-01 02:02:20 +00:00
Merge branch 'BerriAI:main' into patch-1
This commit is contained in:
 Marc Klingen
GitHub
commit
4c1d63040e
551 changed files with 52242 additions and 4906 deletions
|
|
@ -31,6 +31,7 @@ jobs:
|
|||
pip install "google-generativeai>=0.3.2"
|
||||
pip install "google-cloud-aiplatform>=1.38.0"
|
||||
pip install "boto3>=1.28.57"
|
||||
pip install "aioboto3>=12.3.0"
|
||||
pip install langchain
|
||||
pip install "langfuse>=2.0.0"
|
||||
pip install numpydoc
|
||||
|
|
@ -38,8 +39,12 @@ jobs:
|
|||
pip install openai
|
||||
pip install prisma
|
||||
pip install "httpx==0.24.1"
|
||||
pip install "gunicorn==21.2.0"
|
||||
pip install "anyio==3.7.1"
|
||||
pip install "aiodynamo==23.10.1"
|
||||
pip install "asyncio==3.4.3"
|
||||
pip install "apscheduler==3.10.4"
|
||||
pip install "PyGithub==1.59.1"
|
||||
- save_cache:
|
||||
paths:
|
||||
- ./venv
|
||||
|
|
@ -83,6 +88,107 @@ jobs:
|
|||
- store_test_results:
|
||||
path: test-results
|
||||
|
||||
build_and_test:
|
||||
machine:
|
||||
image: ubuntu-2204:2023.10.1
|
||||
working_directory: ~/project
|
||||
steps:
|
||||
- checkout
|
||||
- run:
|
||||
name: Install Docker CLI (In case it's not already installed)
|
||||
command: |
|
||||
sudo apt-get update
|
||||
sudo apt-get install -y docker-ce docker-ce-cli containerd.io
|
||||
- run:
|
||||
name: Install Python 3.9
|
||||
command: |
|
||||
curl https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh --output miniconda.sh
|
||||
bash miniconda.sh -b -p $HOME/miniconda
|
||||
export PATH="$HOME/miniconda/bin:$PATH"
|
||||
conda init bash
|
||||
source ~/.bashrc
|
||||
conda create -n myenv python=3.9 -y
|
||||
conda activate myenv
|
||||
python --version
|
||||
- run:
|
||||
name: Install Dependencies
|
||||
command: |
|
||||
pip install "pytest==7.3.1"
|
||||
pip install "pytest-asyncio==0.21.1"
|
||||
pip install aiohttp
|
||||
pip install openai
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install -r .circleci/requirements.txt
|
||||
pip install "pytest==7.3.1"
|
||||
pip install "pytest-asyncio==0.21.1"
|
||||
pip install mypy
|
||||
pip install "google-generativeai>=0.3.2"
|
||||
pip install "google-cloud-aiplatform>=1.38.0"
|
||||
pip install "boto3>=1.28.57"
|
||||
pip install "aioboto3>=12.3.0"
|
||||
pip install langchain
|
||||
pip install "langfuse>=2.0.0"
|
||||
pip install numpydoc
|
||||
pip install prisma
|
||||
pip install fastapi
|
||||
pip install "httpx==0.24.1"
|
||||
pip install "gunicorn==21.2.0"
|
||||
pip install "anyio==3.7.1"
|
||||
pip install "aiodynamo==23.10.1"
|
||||
pip install "asyncio==3.4.3"
|
||||
pip install "PyGithub==1.59.1"
|
||||
# Run pytest and generate JUnit XML report
|
||||
- run:
|
||||
name: Build Docker image
|
||||
command: docker build -t my-app:latest -f Dockerfile.database .
|
||||
- run:
|
||||
name: Run Docker container
|
||||
command: |
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e DATABASE_URL=$PROXY_DOCKER_DB_URL \
|
||||
-e AZURE_API_KEY=$AZURE_API_KEY \
|
||||
-e AZURE_FRANCE_API_KEY=$AZURE_FRANCE_API_KEY \
|
||||
-e AZURE_EUROPE_API_KEY=$AZURE_EUROPE_API_KEY \
|
||||
-e AWS_ACCESS_KEY_ID=$AWS_ACCESS_KEY_ID \
|
||||
-e AWS_SECRET_ACCESS_KEY=$AWS_SECRET_ACCESS_KEY \
|
||||
-e AWS_REGION_NAME=$AWS_REGION_NAME \
|
||||
-e OPENAI_API_KEY=$OPENAI_API_KEY \
|
||||
--name my-app \
|
||||
-v $(pwd)/proxy_server_config.yaml:/app/config.yaml \
|
||||
my-app:latest \
|
||||
--config /app/config.yaml \
|
||||
--port 4000 \
|
||||
--num_workers 8 \
|
||||
--detailed_debug \
|
||||
--run_gunicorn \
|
||||
- run:
|
||||
name: Install curl and dockerize
|
||||
command: |
|
||||
sudo apt-get update
|
||||
sudo apt-get install -y curl
|
||||
sudo wget https://github.com/jwilder/dockerize/releases/download/v0.6.1/dockerize-linux-amd64-v0.6.1.tar.gz
|
||||
sudo tar -C /usr/local/bin -xzvf dockerize-linux-amd64-v0.6.1.tar.gz
|
||||
sudo rm dockerize-linux-amd64-v0.6.1.tar.gz
|
||||
- run:
|
||||
name: Start outputting logs
|
||||
command: docker logs -f my-app
|
||||
background: true
|
||||
- run:
|
||||
name: Wait for app to be ready
|
||||
command: dockerize -wait http://localhost:4000 -timeout 1m
|
||||
- run:
|
||||
name: Run tests
|
||||
command: |
|
||||
pwd
|
||||
ls
|
||||
python -m pytest -vv tests/ -x --junitxml=test-results/junit.xml --durations=5
|
||||
no_output_timeout: 120m
|
||||
|
||||
# Store test results
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
|
||||
publish_to_pypi:
|
||||
docker:
|
||||
- image: cimg/python:3.8
|
||||
|
|
@ -164,9 +270,16 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- build_and_test:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- publish_to_pypi:
|
||||
requires:
|
||||
- local_testing
|
||||
- build_and_test
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
|
|
|
|||
|
|
@ -10,4 +10,5 @@ anthropic
|
|||
boto3
|
||||
orjson
|
||||
pydantic
|
||||
google-cloud-aiplatform
|
||||
google-cloud-aiplatform
|
||||
redisvl==0.0.7 # semantic caching
|
||||
77
.github/actions/helm-oci-chart-releaser/action.yml
vendored
Normal file
77
.github/actions/helm-oci-chart-releaser/action.yml
vendored
Normal file
|
|
@ -0,0 +1,77 @@
|
|||
name: Helm OCI Chart Releaser
|
||||
description: Push Helm charts to OCI-based (Docker) registries
|
||||
author: sergeyshaykhullin
|
||||
branding:
|
||||
color: yellow
|
||||
icon: upload-cloud
|
||||
inputs:
|
||||
name:
|
||||
required: true
|
||||
description: Chart name
|
||||
repository:
|
||||
required: true
|
||||
description: Chart repository name
|
||||
tag:
|
||||
required: true
|
||||
description: Chart version
|
||||
app_version:
|
||||
required: true
|
||||
description: App version
|
||||
path:
|
||||
required: false
|
||||
description: Chart path (Default 'charts/{name}')
|
||||
registry:
|
||||
required: true
|
||||
description: OCI registry
|
||||
registry_username:
|
||||
required: true
|
||||
description: OCI registry username
|
||||
registry_password:
|
||||
required: true
|
||||
description: OCI registry password
|
||||
update_dependencies:
|
||||
required: false
|
||||
default: 'false'
|
||||
description: Update chart dependencies before packaging (Default 'false')
|
||||
outputs:
|
||||
image:
|
||||
value: ${{ steps.output.outputs.image }}
|
||||
description: Chart image (Default '{registry}/{repository}/{image}:{tag}')
|
||||
runs:
|
||||
using: composite
|
||||
steps:
|
||||
- name: Helm | Login
|
||||
shell: bash
|
||||
run: echo ${{ inputs.registry_password }} | helm registry login -u ${{ inputs.registry_username }} --password-stdin ${{ inputs.registry }}
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
- name: Helm | Dependency
|
||||
if: inputs.update_dependencies == 'true'
|
||||
shell: bash
|
||||
run: helm dependency update ${{ inputs.path == null && format('{0}/{1}', 'charts', inputs.name) || inputs.path }}
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
- name: Helm | Package
|
||||
shell: bash
|
||||
run: helm package ${{ inputs.path == null && format('{0}/{1}', 'charts', inputs.name) || inputs.path }} --version ${{ inputs.tag }} --app-version ${{ inputs.app_version }}
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
- name: Helm | Push
|
||||
shell: bash
|
||||
run: helm push ${{ inputs.name }}-${{ inputs.tag }}.tgz oci://${{ inputs.registry }}/${{ inputs.repository }}
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
- name: Helm | Logout
|
||||
shell: bash
|
||||
run: helm registry logout ${{ inputs.registry }}
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
- name: Helm | Output
|
||||
id: output
|
||||
shell: bash
|
||||
run: echo "image=${{ inputs.registry }}/${{ inputs.repository }}/${{ inputs.name }}:${{ inputs.tag }}" >> $GITHUB_OUTPUT
|
||||
0
template.yaml → .github/template.yaml
vendored
0
template.yaml → .github/template.yaml
vendored
90
.github/workflows/ghcr_deploy.yml
vendored
90
.github/workflows/ghcr_deploy.yml
vendored
|
|
@ -13,6 +13,35 @@ env:
|
|||
|
||||
# There is a single job in this workflow. It's configured to run on the latest available version of Ubuntu.
|
||||
jobs:
|
||||
docker-hub-deploy:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
-
|
||||
name: Set up QEMU
|
||||
uses: docker/setup-qemu-action@v3
|
||||
-
|
||||
name: Set up Docker Buildx
|
||||
uses: docker/setup-buildx-action@v3
|
||||
-
|
||||
name: Login to Docker Hub
|
||||
uses: docker/login-action@v3
|
||||
with:
|
||||
username: ${{ secrets.DOCKERHUB_USERNAME }}
|
||||
password: ${{ secrets.DOCKERHUB_TOKEN }}
|
||||
-
|
||||
name: Build and push
|
||||
uses: docker/build-push-action@v5
|
||||
with:
|
||||
push: true
|
||||
tags: litellm/litellm:${{ github.event.inputs.tag || 'latest' }}
|
||||
-
|
||||
name: Build and push litellm-database image
|
||||
uses: docker/build-push-action@v5
|
||||
with:
|
||||
push: true
|
||||
file: Dockerfile.database
|
||||
tags: litellm/litellm-database:${{ github.event.inputs.tag || 'latest' }}
|
||||
|
||||
build-and-push-image:
|
||||
runs-on: ubuntu-latest
|
||||
# Sets the permissions granted to the `GITHUB_TOKEN` for the actions in this job.
|
||||
|
|
@ -36,46 +65,23 @@ jobs:
|
|||
uses: docker/metadata-action@9ec57ed1fcdbf14dcef7dfbe97b2010124a938b7
|
||||
with:
|
||||
images: ${{ env.REGISTRY }}/${{ env.IMAGE_NAME }}
|
||||
# Configure multi platform Docker builds
|
||||
- name: Set up QEMU
|
||||
uses: docker/setup-qemu-action@e0e4588fad221d38ee467c0bffd91115366dc0c5
|
||||
- name: Set up Docker Buildx
|
||||
uses: docker/setup-buildx-action@edfb0fe6204400c56fbfd3feba3fe9ad1adfa345
|
||||
# This step uses the `docker/build-push-action` action to build the image, based on your repository's `Dockerfile`. If the build succeeds, it pushes the image to GitHub Packages.
|
||||
# It uses the `context` parameter to define the build's context as the set of files located in the specified path. For more information, see "[Usage](https://github.com/docker/build-push-action#usage)" in the README of the `docker/build-push-action` repository.
|
||||
# It uses the `tags` and `labels` parameters to tag and label the image with the output from the "meta" step.
|
||||
- name: Build and push Docker image
|
||||
uses: docker/build-push-action@f2a1d5e99d037542a71f64918e516c093c6f3fc4
|
||||
uses: docker/build-push-action@4976231911ebf5f32aad765192d35f942aa48cb8
|
||||
with:
|
||||
context: .
|
||||
push: true
|
||||
tags: ${{ steps.meta.outputs.tags }}-${{ github.event.inputs.tag || 'latest' }} # if a tag is provided, use that, otherwise use the release tag, and if neither is available, use 'latest'
|
||||
tags: ${{ steps.meta.outputs.tags }}-${{ github.event.inputs.tag || 'latest' }}, ${{ steps.meta.outputs.tags }}-latest # if a tag is provided, use that, otherwise use the release tag, and if neither is available, use 'latest'
|
||||
labels: ${{ steps.meta.outputs.labels }}
|
||||
build-and-push-image-alpine:
|
||||
runs-on: ubuntu-latest
|
||||
permissions:
|
||||
contents: read
|
||||
packages: write
|
||||
steps:
|
||||
- name: Checkout repository
|
||||
uses: actions/checkout@v4
|
||||
|
||||
- name: Log in to the Container registry
|
||||
uses: docker/login-action@65b78e6e13532edd9afa3aa52ac7964289d1a9c1
|
||||
with:
|
||||
registry: ${{ env.REGISTRY }}
|
||||
username: ${{ github.actor }}
|
||||
password: ${{ secrets.GITHUB_TOKEN }}
|
||||
|
||||
- name: Extract metadata (tags, labels) for Alpine Dockerfile
|
||||
id: meta-alpine
|
||||
uses: docker/metadata-action@9ec57ed1fcdbf14dcef7dfbe97b2010124a938b7
|
||||
with:
|
||||
images: ${{ env.REGISTRY }}/${{ env.IMAGE_NAME }}-alpine
|
||||
|
||||
- name: Build and push Alpine Docker image
|
||||
uses: docker/build-push-action@f2a1d5e99d037542a71f64918e516c093c6f3fc4
|
||||
with:
|
||||
context: .
|
||||
dockerfile: Dockerfile.alpine
|
||||
push: true
|
||||
tags: ${{ steps.meta-alpine.outputs.tags }}-${{ github.event.inputs.tag || 'latest' }}
|
||||
labels: ${{ steps.meta-alpine.outputs.labels }}
|
||||
platforms: local,linux/amd64,linux/arm64,linux/arm64/v8
|
||||
|
||||
build-and-push-image-database:
|
||||
runs-on: ubuntu-latest
|
||||
permissions:
|
||||
|
|
@ -104,10 +110,11 @@ jobs:
|
|||
context: .
|
||||
file: Dockerfile.database
|
||||
push: true
|
||||
tags: ${{ steps.meta-database.outputs.tags }}-${{ github.event.inputs.tag || 'latest' }}, latest
|
||||
tags: ${{ steps.meta-database.outputs.tags }}-${{ github.event.inputs.tag || 'latest' }}, ${{ steps.meta-database.outputs.tags }}-latest
|
||||
labels: ${{ steps.meta-database.outputs.labels }}
|
||||
release:
|
||||
name: "New LiteLLM Release"
|
||||
needs: [docker-hub-deploy, build-and-push-image, build-and-push-image-database]
|
||||
|
||||
runs-on: "ubuntu-latest"
|
||||
|
||||
|
|
@ -139,3 +146,20 @@ jobs:
|
|||
} catch (error) {
|
||||
core.setFailed(error.message);
|
||||
}
|
||||
- name: Github Releases To Discord
|
||||
env:
|
||||
WEBHOOK_URL: ${{ secrets.WEBHOOK_URL }}
|
||||
run: |
|
||||
curl -H "Content-Type: application/json" -X POST -d '{
|
||||
"content": "||@everyone||",
|
||||
"username": "Release Changelog",
|
||||
"avatar_url": "https://cdn.discordapp.com/avatars/487431320314576937/bd64361e4ba6313d561d54e78c9e7171.png",
|
||||
"embeds": [
|
||||
{
|
||||
"title": "Changelog",
|
||||
"description": "This is the changelog for the latest release.",
|
||||
"color": 2105893
|
||||
}
|
||||
]
|
||||
}' $WEBHOOK_URL
|
||||
|
||||
|
|
|
|||
64
.github/workflows/ghcr_helm_deploy.yml
vendored
Normal file
64
.github/workflows/ghcr_helm_deploy.yml
vendored
Normal file
|
|
@ -0,0 +1,64 @@
|
|||
# this workflow is triggered by an API call when there is a new PyPI release of LiteLLM
|
||||
name: Build, Publish LiteLLM Helm Chart. New Release
|
||||
on:
|
||||
workflow_dispatch:
|
||||
inputs:
|
||||
chartVersion:
|
||||
description: "Update the helm chart's version to this"
|
||||
|
||||
# Defines two custom environment variables for the workflow. Used for the Container registry domain, and a name for the Docker image that this workflow builds.
|
||||
env:
|
||||
REGISTRY: ghcr.io
|
||||
IMAGE_NAME: ${{ github.repository }}
|
||||
REPO_OWNER: ${{github.repository_owner}}
|
||||
|
||||
# There is a single job in this workflow. It's configured to run on the latest available version of Ubuntu.
|
||||
jobs:
|
||||
build-and-push-helm-chart:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Checkout repository
|
||||
uses: actions/checkout@v4
|
||||
|
||||
- name: Log in to the Container registry
|
||||
uses: docker/login-action@65b78e6e13532edd9afa3aa52ac7964289d1a9c1
|
||||
with:
|
||||
registry: ${{ env.REGISTRY }}
|
||||
username: ${{ github.actor }}
|
||||
password: ${{ secrets.GITHUB_TOKEN }}
|
||||
|
||||
- name: lowercase github.repository_owner
|
||||
run: |
|
||||
echo "REPO_OWNER=`echo ${{github.repository_owner}} | tr '[:upper:]' '[:lower:]'`" >>${GITHUB_ENV}
|
||||
|
||||
- name: Get LiteLLM Latest Tag
|
||||
id: current_app_tag
|
||||
uses: WyriHaximus/github-action-get-previous-tag@v1.3.0
|
||||
|
||||
- name: Get last published chart version
|
||||
id: current_version
|
||||
shell: bash
|
||||
run: helm show chart oci://${{ env.REGISTRY }}/${{ env.REPO_OWNER }}/litellm-helm | grep '^version:' | awk 'BEGIN{FS=":"}{print "current-version="$2}' | tr -d " " | tee -a $GITHUB_OUTPUT
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
# Automatically update the helm chart version one "patch" level
|
||||
- name: Bump release version
|
||||
id: bump_version
|
||||
uses: christian-draeger/increment-semantic-version@1.1.0
|
||||
with:
|
||||
current-version: ${{ steps.current_version.outputs.current-version || '0.1.0' }}
|
||||
version-fragment: 'bug'
|
||||
|
||||
- uses: ./.github/actions/helm-oci-chart-releaser
|
||||
with:
|
||||
name: litellm-helm
|
||||
repository: ${{ env.REPO_OWNER }}
|
||||
tag: ${{ github.event.inputs.chartVersion || steps.bump_version.outputs.next-version || '0.1.0' }}
|
||||
app_version: ${{ steps.current_app_tag.outputs.tag || 'latest' }}
|
||||
path: deploy/charts/litellm-helm
|
||||
registry: ${{ env.REGISTRY }}
|
||||
registry_username: ${{ github.actor }}
|
||||
registry_password: ${{ secrets.GITHUB_TOKEN }}
|
||||
update_dependencies: true
|
||||
|
||||
12
.gitignore
vendored
12
.gitignore
vendored
|
|
@ -32,3 +32,15 @@ proxy_server_config_@.yaml
|
|||
proxy_server_config_2.yaml
|
||||
litellm/proxy/secret_managers/credentials.json
|
||||
hosted_config.yaml
|
||||
litellm/proxy/tests/node_modules
|
||||
litellm/proxy/tests/package.json
|
||||
litellm/proxy/tests/package-lock.json
|
||||
ui/litellm-dashboard/.next
|
||||
ui/litellm-dashboard/node_modules
|
||||
ui/litellm-dashboard/next-env.d.ts
|
||||
ui/litellm-dashboard/package.json
|
||||
ui/litellm-dashboard/package-lock.json
|
||||
deploy/charts/litellm/*.tgz
|
||||
deploy/charts/litellm/charts/*
|
||||
deploy/charts/*.tgz
|
||||
litellm/proxy/vertex_key.json
|
||||
|
|
|
|||
|
|
@ -1,15 +1,21 @@
|
|||
repos:
|
||||
- repo: https://github.com/psf/black
|
||||
rev: stable
|
||||
rev: 24.2.0
|
||||
hooks:
|
||||
- id: black
|
||||
- repo: https://github.com/pycqa/flake8
|
||||
rev: 3.8.4 # The version of flake8 to use
|
||||
rev: 7.0.0 # The version of flake8 to use
|
||||
hooks:
|
||||
- id: flake8
|
||||
exclude: ^litellm/tests/|^litellm/proxy/proxy_cli.py|^litellm/integrations/|^litellm/proxy/tests/
|
||||
additional_dependencies: [flake8-print]
|
||||
files: litellm/.*\.py
|
||||
- repo: local
|
||||
hooks:
|
||||
- id: check-files-match
|
||||
name: Check if files match
|
||||
entry: python3 ci_cd/check_files_match.py
|
||||
language: system
|
||||
- repo: local
|
||||
hooks:
|
||||
- id: mypy
|
||||
|
|
|
|||
16
Dockerfile
16
Dockerfile
|
|
@ -20,6 +20,9 @@ RUN pip install --upgrade pip && \
|
|||
# Copy the current directory contents into the container at /app
|
||||
COPY . .
|
||||
|
||||
# Build Admin UI
|
||||
RUN chmod +x build_admin_ui.sh && ./build_admin_ui.sh
|
||||
|
||||
# Build the package
|
||||
RUN rm -rf dist/* && python -m build
|
||||
|
||||
|
|
@ -32,6 +35,12 @@ RUN pip install dist/*.whl
|
|||
# install dependencies as wheels
|
||||
RUN pip wheel --no-cache-dir --wheel-dir=/wheels/ -r requirements.txt
|
||||
|
||||
# install semantic-cache [Experimental]- we need this here and not in requirements.txt because redisvl pins to pydantic 1.0
|
||||
RUN pip install redisvl==0.0.7 --no-deps
|
||||
|
||||
# Build Admin UI
|
||||
RUN chmod +x build_admin_ui.sh && ./build_admin_ui.sh
|
||||
|
||||
# Runtime stage
|
||||
FROM $LITELLM_RUNTIME_IMAGE as runtime
|
||||
|
||||
|
|
@ -51,8 +60,5 @@ RUN chmod +x entrypoint.sh
|
|||
|
||||
EXPOSE 4000/tcp
|
||||
|
||||
# Set your entrypoint and command
|
||||
CMD [ \
|
||||
"sh", "-c", \
|
||||
"if [ -n \"$DATABASE_URL\" ]; then ./entrypoint.sh; else litellm --port 4000 --num_workers 8; fi" \
|
||||
]
|
||||
ENTRYPOINT ["litellm"]
|
||||
CMD ["--port", "4000", "--config", "./proxy_server_config.yaml", "--detailed_debug", "--run_gunicorn"]
|
||||
|
|
@ -1,8 +1,8 @@
|
|||
# Base image for building
|
||||
ARG LITELLM_BUILD_IMAGE=python:3.9-alpine
|
||||
ARG LITELLM_BUILD_IMAGE=python:3.11-alpine
|
||||
|
||||
# Runtime image
|
||||
ARG LITELLM_RUNTIME_IMAGE=python:3.9-alpine
|
||||
ARG LITELLM_RUNTIME_IMAGE=python:3.11-alpine
|
||||
|
||||
# Builder stage
|
||||
FROM $LITELLM_BUILD_IMAGE as builder
|
||||
|
|
|
|||
|
|
@ -20,6 +20,9 @@ RUN pip install --upgrade pip && \
|
|||
# Copy the current directory contents into the container at /app
|
||||
COPY . .
|
||||
|
||||
# Build Admin UI
|
||||
RUN chmod +x build_admin_ui.sh && ./build_admin_ui.sh
|
||||
|
||||
# Build the package
|
||||
RUN rm -rf dist/* && python -m build
|
||||
|
||||
|
|
@ -47,11 +50,19 @@ COPY --from=builder /wheels/ /wheels/
|
|||
# Install the built wheel using pip; again using a wildcard if it's the only file
|
||||
RUN pip install *.whl /wheels/* --no-index --find-links=/wheels/ && rm -f *.whl && rm -rf /wheels
|
||||
|
||||
# install semantic-cache [Experimental]- we need this here and not in requirements.txt because redisvl pins to pydantic 1.0
|
||||
RUN pip install redisvl==0.0.7 --no-deps
|
||||
|
||||
# Build Admin UI
|
||||
RUN chmod +x build_admin_ui.sh && ./build_admin_ui.sh
|
||||
|
||||
# Generate prisma client
|
||||
RUN prisma generate
|
||||
RUN chmod +x entrypoint.sh
|
||||
|
||||
EXPOSE 4000/tcp
|
||||
|
||||
# Set your entrypoint and command
|
||||
CMD ["./entrypoint.sh"]
|
||||
# # Set your entrypoint and command
|
||||
|
||||
ENTRYPOINT ["litellm"]
|
||||
CMD ["--port", "4000", "--run_gunicorn"]
|
||||
|
|
|
|||
5
LICENSE
5
LICENSE
|
|
@ -1,3 +1,8 @@
|
|||
Portions of this software are licensed as follows:
|
||||
|
||||
* All content that resides under the "enterprise/" directory of this repository, if that directory exists, is licensed under the license defined in "enterprise/LICENSE".
|
||||
* Content outside of the above mentioned directories or restrictions above is available under the MIT license as defined below.
|
||||
---
|
||||
MIT License
|
||||
|
||||
Copyright (c) 2023 Berri AI
|
||||
|
|
|
|||
45
README.md
45
README.md
|
|
@ -5,7 +5,7 @@
|
|||
<p align="center">Call all LLM APIs using the OpenAI format [Bedrock, Huggingface, VertexAI, TogetherAI, Azure, OpenAI, etc.]
|
||||
<br>
|
||||
</p>
|
||||
<h4 align="center"><a href="https://docs.litellm.ai/docs/simple_proxy" target="_blank">OpenAI Proxy Server</a></h4>
|
||||
<h4 align="center"><a href="https://docs.litellm.ai/docs/simple_proxy" target="_blank">OpenAI Proxy Server</a> | <a href="https://docs.litellm.ai/docs/enterprise"target="_blank">Enterprise Tier</a></h4>
|
||||
<h4 align="center">
|
||||
<a href="https://pypi.org/project/litellm/" target="_blank">
|
||||
<img src="https://img.shields.io/pypi/v/litellm.svg" alt="PyPI Version">
|
||||
|
|
@ -28,10 +28,14 @@ LiteLLM manages:
|
|||
- Translate inputs to provider's `completion`, `embedding`, and `image_generation` endpoints
|
||||
- [Consistent output](https://docs.litellm.ai/docs/completion/output), text responses will always be available at `['choices'][0]['message']['content']`
|
||||
- Retry/fallback logic across multiple deployments (e.g. Azure/OpenAI) - [Router](https://docs.litellm.ai/docs/routing)
|
||||
- Set Budgets & Rate limits per project, api key, model [OpenAI Proxy Server](https://docs.litellm.ai/docs/simple_proxy)
|
||||
|
||||
|
||||
[**Jump to OpenAI Proxy Docs**](https://github.com/BerriAI/litellm?tab=readme-ov-file#openai-proxy---docs) <br>
|
||||
[**Jump to Supported LLM Providers**](https://github.com/BerriAI/litellm?tab=readme-ov-file#supported-provider-docs)
|
||||
|
||||
Support for more providers. Missing a provider or LLM Platform, raise a [feature request](https://github.com/BerriAI/litellm/issues/new?assignees=&labels=enhancement&projects=&template=feature_request.yml&title=%5BFeature%5D%3A+).
|
||||
|
||||
# Usage ([**Docs**](https://docs.litellm.ai/docs/))
|
||||
> [!IMPORTANT]
|
||||
> LiteLLM v1.0.0 now requires `openai>=1.0.0`. Migration guide [here](https://docs.litellm.ai/docs/migration)
|
||||
|
|
@ -64,6 +68,8 @@ response = completion(model="command-nightly", messages=messages)
|
|||
print(response)
|
||||
```
|
||||
|
||||
Call any model supported by a provider, with `model=<provider_name>/<model_name>`. There might be provider-specific details here, so refer to [provider docs for more information](https://docs.litellm.ai/docs/providers)
|
||||
|
||||
## Async ([Docs](https://docs.litellm.ai/docs/completion/stream#async-completion))
|
||||
|
||||
```python
|
||||
|
|
@ -96,7 +102,7 @@ for part in response:
|
|||
```
|
||||
|
||||
## Logging Observability ([Docs](https://docs.litellm.ai/docs/observability/callbacks))
|
||||
LiteLLM exposes pre defined callbacks to send data to Langfuse, LLMonitor, Helicone, Promptlayer, Traceloop, Slack
|
||||
LiteLLM exposes pre defined callbacks to send data to Langfuse, DynamoDB, s3 Buckets, LLMonitor, Helicone, Promptlayer, Traceloop, Athina, Slack
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
|
|
@ -104,11 +110,12 @@ from litellm import completion
|
|||
os.environ["LANGFUSE_PUBLIC_KEY"] = ""
|
||||
os.environ["LANGFUSE_SECRET_KEY"] = ""
|
||||
os.environ["LLMONITOR_APP_ID"] = "your-llmonitor-app-id"
|
||||
os.environ["ATHINA_API_KEY"] = "your-athina-api-key"
|
||||
|
||||
os.environ["OPENAI_API_KEY"]
|
||||
|
||||
# set callbacks
|
||||
litellm.success_callback = ["langfuse", "llmonitor"] # log input/output to langfuse, llmonitor, supabase
|
||||
litellm.success_callback = ["langfuse", "llmonitor", "athina"] # log input/output to langfuse, llmonitor, supabase, athina etc
|
||||
|
||||
#openai call
|
||||
response = completion(model="gpt-3.5-turbo", messages=[{"role": "user", "content": "Hi 👋 - i'm openai"}])
|
||||
|
|
@ -116,7 +123,7 @@ response = completion(model="gpt-3.5-turbo", messages=[{"role": "user", "content
|
|||
|
||||
# OpenAI Proxy - ([Docs](https://docs.litellm.ai/docs/simple_proxy))
|
||||
|
||||
Track spend across multiple projects/people
|
||||
Set Budgets & Rate limits across multiple projects
|
||||
|
||||
The proxy provides:
|
||||
1. [Hooks for auth](https://docs.litellm.ai/docs/proxy/virtual_keys#custom-auth)
|
||||
|
|
@ -155,7 +162,10 @@ print(response)
|
|||
```
|
||||
|
||||
## Proxy Key Management ([Docs](https://docs.litellm.ai/docs/proxy/virtual_keys))
|
||||
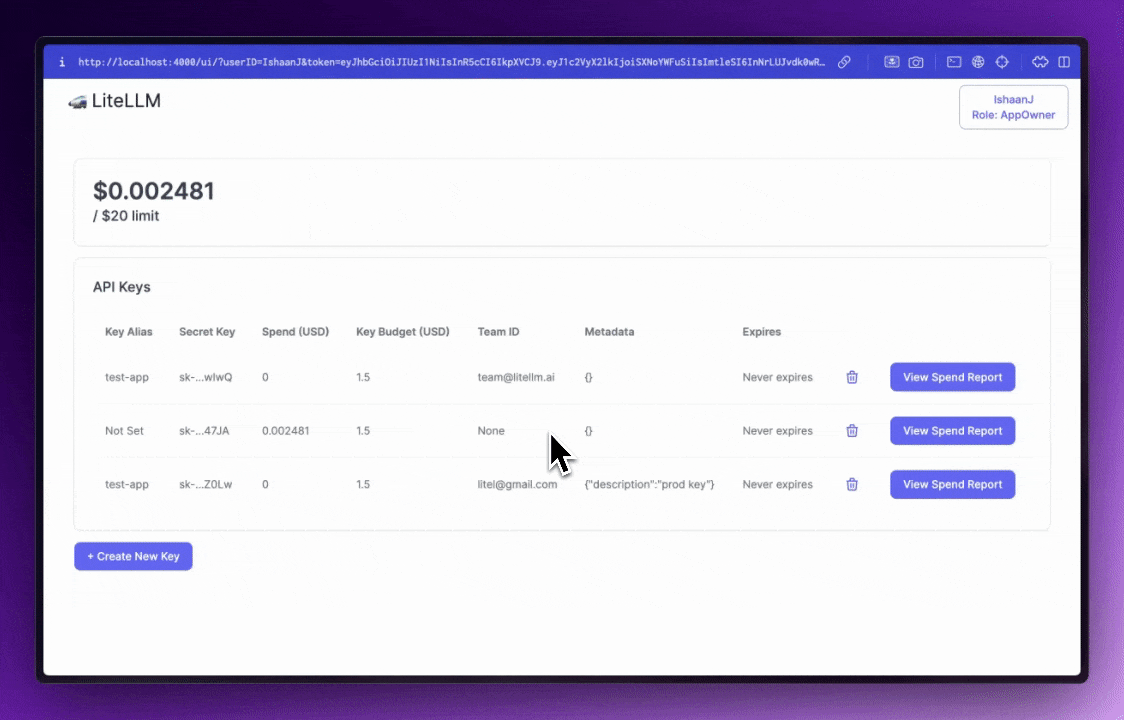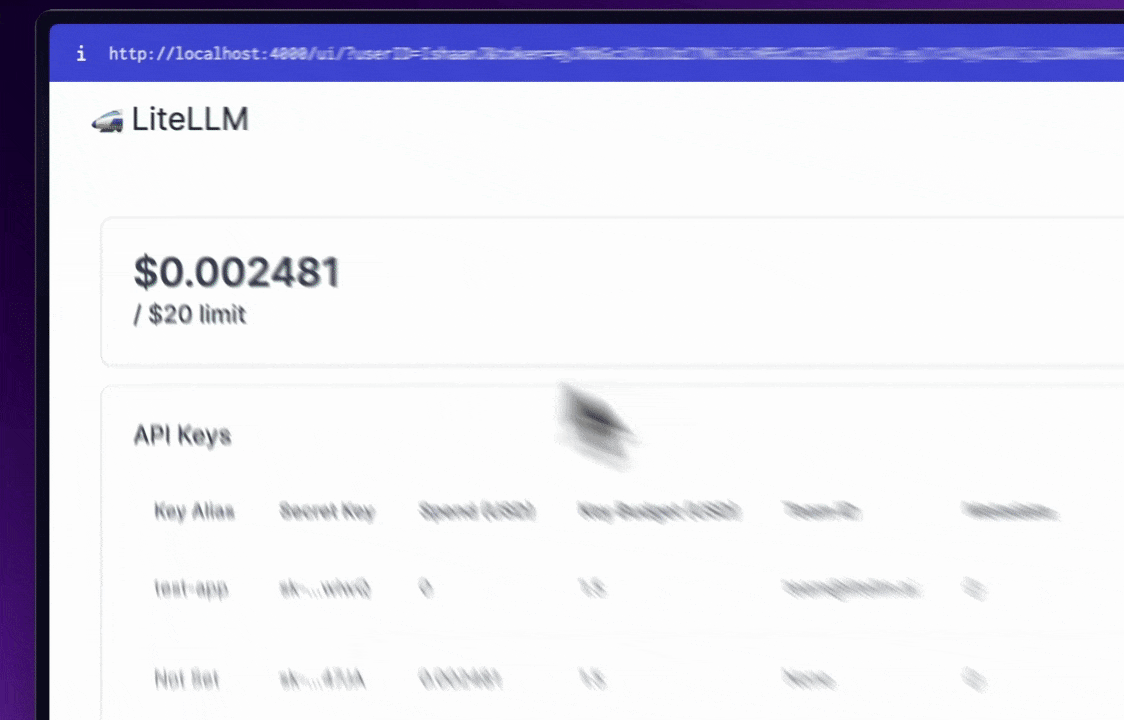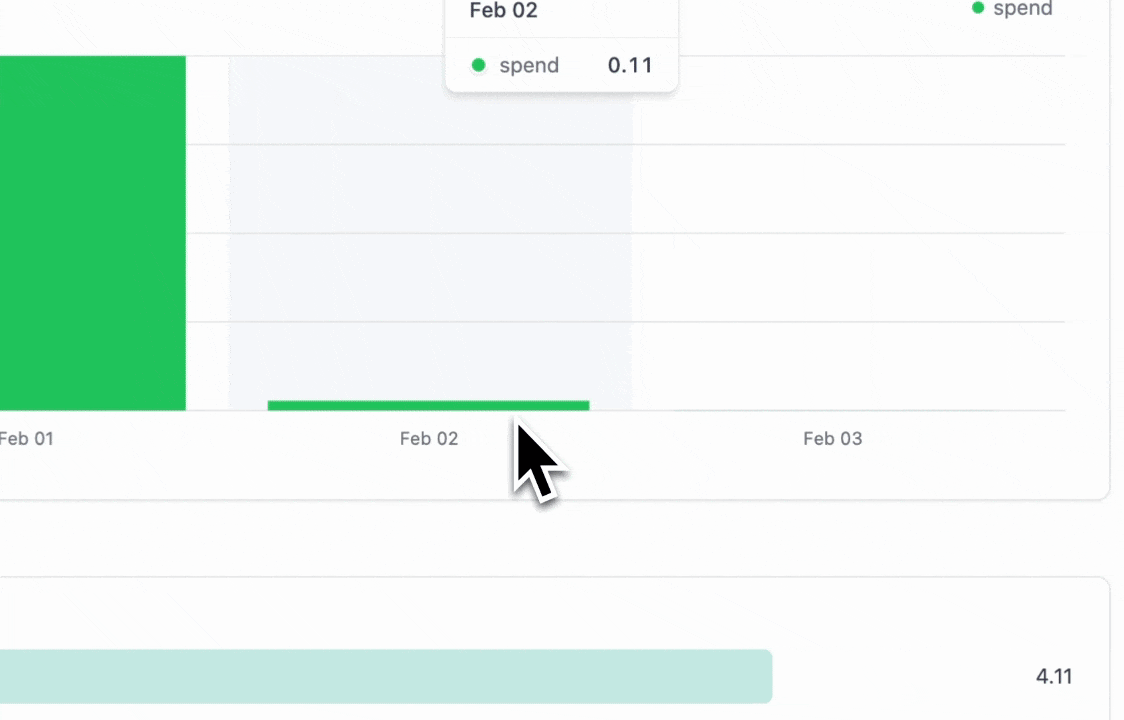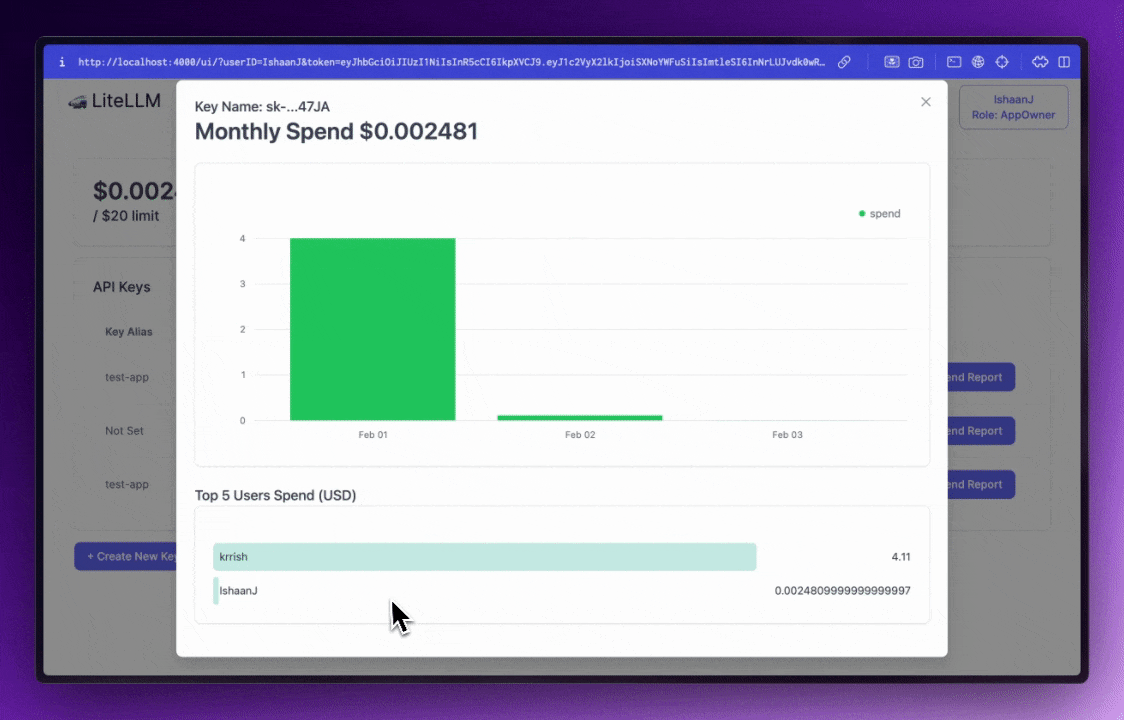
Track Spend, Set budgets and create virtual keys for the proxy
|
||||
UI on `/ui` on your proxy server
|
||||
|
||||
|
||||
Set budgets and rate limits across multiple projects
|
||||
`POST /key/generate`
|
||||
|
||||
### Request
|
||||
|
|
@ -174,17 +184,6 @@ curl 'http://0.0.0.0:8000/key/generate' \
|
|||
}
|
||||
```
|
||||
|
||||
### [Beta] Proxy UI
|
||||
|
||||
A simple UI to add new models and let your users create keys.
|
||||
|
||||
Live here: https://dashboard.litellm.ai/
|
||||
|
||||
Code: https://github.com/BerriAI/litellm/tree/main/ui
|
||||
|
||||
|
||||
<img width="1672" alt="Screenshot 2023-12-26 at 8 33 53 AM" src="https://github.com/BerriAI/litellm/assets/17561003/274254d8-c5fe-4645-9123-100045a7fb21">
|
||||
|
||||
## Supported Providers ([Docs](https://docs.litellm.ai/docs/providers))
|
||||
| Provider | [Completion](https://docs.litellm.ai/docs/#basic-usage) | [Streaming](https://docs.litellm.ai/docs/completion/stream#streaming-responses) | [Async Completion](https://docs.litellm.ai/docs/completion/stream#async-completion) | [Async Streaming](https://docs.litellm.ai/docs/completion/stream#async-streaming) | [Async Embedding](https://docs.litellm.ai/docs/embedding/supported_embedding) | [Async Image Generation](https://docs.litellm.ai/docs/image_generation) |
|
||||
| ------------- | ------------- | ------------- | ------------- | ------------- | ------------- | ------------- |
|
||||
|
|
@ -212,6 +211,7 @@ Code: https://github.com/BerriAI/litellm/tree/main/ui
|
|||
| [ollama](https://docs.litellm.ai/docs/providers/ollama) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [deepinfra](https://docs.litellm.ai/docs/providers/deepinfra) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [perplexity-ai](https://docs.litellm.ai/docs/providers/perplexity) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [Groq AI](https://docs.litellm.ai/docs/providers/groq) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [anyscale](https://docs.litellm.ai/docs/providers/anyscale) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [voyage ai](https://docs.litellm.ai/docs/providers/voyage) | | | | | ✅ |
|
||||
| [xinference [Xorbits Inference]](https://docs.litellm.ai/docs/providers/xinference) | | | | | ✅ |
|
||||
|
|
@ -245,6 +245,19 @@ Step 4: Submit a PR with your changes! 🚀
|
|||
- push your fork to your GitHub repo
|
||||
- submit a PR from there
|
||||
|
||||
# Enterprise
|
||||
For companies that need better security, user management and professional support
|
||||
|
||||
[Talk to founders](https://calendly.com/d/4mp-gd3-k5k/litellm-1-1-onboarding-chat)
|
||||
|
||||
This covers:
|
||||
- ✅ **Features under the [LiteLLM Commercial License](https://docs.litellm.ai/docs/proxy/enterprise):**
|
||||
- ✅ **Feature Prioritization**
|
||||
- ✅ **Custom Integrations**
|
||||
- ✅ **Professional Support - Dedicated discord + slack**
|
||||
- ✅ **Custom SLAs**
|
||||
- ✅ **Secure access with Single Sign-On**
|
||||
|
||||
# Support / talk with founders
|
||||
- [Schedule Demo 👋](https://calendly.com/d/4mp-gd3-k5k/berriai-1-1-onboarding-litellm-hosted-version)
|
||||
- [Community Discord 💭](https://discord.gg/wuPM9dRgDw)
|
||||
|
|
|
|||
62
build_admin_ui.sh
Executable file
62
build_admin_ui.sh
Executable file
|
|
@ -0,0 +1,62 @@
|
|||
#!/bin/bash
|
||||
|
||||
# # try except this script
|
||||
# set -e
|
||||
|
||||
# print current dir
|
||||
echo
|
||||
pwd
|
||||
|
||||
|
||||
# only run this step for litellm enterprise, we run this if enterprise/enterprise_ui/_enterprise.json exists
|
||||
if [ ! -f "enterprise/enterprise_ui/enterprise_colors.json" ]; then
|
||||
echo "Admin UI - using default LiteLLM UI"
|
||||
exit 0
|
||||
fi
|
||||
|
||||
echo "Building Custom Admin UI..."
|
||||
|
||||
# Install dependencies
|
||||
# Check if we are on macOS
|
||||
if [[ "$(uname)" == "Darwin" ]]; then
|
||||
# Install dependencies using Homebrew
|
||||
if ! command -v brew &> /dev/null; then
|
||||
echo "Error: Homebrew not found. Please install Homebrew and try again."
|
||||
exit 1
|
||||
fi
|
||||
brew update
|
||||
brew install curl
|
||||
else
|
||||
# Assume Linux, try using apt-get
|
||||
if command -v apt-get &> /dev/null; then
|
||||
apt-get update
|
||||
apt-get install -y curl
|
||||
elif command -v apk &> /dev/null; then
|
||||
# Try using apk if apt-get is not available
|
||||
apk update
|
||||
apk add curl
|
||||
else
|
||||
echo "Error: Unsupported package manager. Cannot install dependencies."
|
||||
exit 1
|
||||
fi
|
||||
fi
|
||||
curl -o- https://raw.githubusercontent.com/nvm-sh/nvm/v0.38.0/install.sh | bash
|
||||
source ~/.nvm/nvm.sh
|
||||
nvm install v18.17.0
|
||||
nvm use v18.17.0
|
||||
npm install -g npm
|
||||
|
||||
# copy _enterprise.json from this directory to /ui/litellm-dashboard, and rename it to ui_colors.json
|
||||
cp enterprise/enterprise_ui/enterprise_colors.json ui/litellm-dashboard/ui_colors.json
|
||||
|
||||
# cd in to /ui/litellm-dashboard
|
||||
cd ui/litellm-dashboard
|
||||
|
||||
# ensure have access to build_ui.sh
|
||||
chmod +x ./build_ui.sh
|
||||
|
||||
# run ./build_ui.sh
|
||||
./build_ui.sh
|
||||
|
||||
# return to root directory
|
||||
cd ../..
|
||||
32
ci_cd/check_files_match.py
Normal file
32
ci_cd/check_files_match.py
Normal file
|
|
@ -0,0 +1,32 @@
|
|||
import sys
|
||||
import filecmp
|
||||
import shutil
|
||||
|
||||
|
||||
def main(argv=None):
|
||||
print(
|
||||
"Comparing model_prices_and_context_window and litellm/model_prices_and_context_window_backup.json files... checking if they match."
|
||||
)
|
||||
|
||||
file1 = "model_prices_and_context_window.json"
|
||||
file2 = "litellm/model_prices_and_context_window_backup.json"
|
||||
|
||||
cmp_result = filecmp.cmp(file1, file2, shallow=False)
|
||||
|
||||
if cmp_result:
|
||||
print(f"Passed! Files {file1} and {file2} match.")
|
||||
return 0
|
||||
else:
|
||||
print(
|
||||
f"Failed! Files {file1} and {file2} do not match. Copying content from {file1} to {file2}."
|
||||
)
|
||||
copy_content(file1, file2)
|
||||
return 1
|
||||
|
||||
|
||||
def copy_content(source, destination):
|
||||
shutil.copy2(source, destination)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
sys.exit(main())
|
||||
|
|
@ -0,0 +1,76 @@
|
|||
import sys, os
|
||||
import traceback
|
||||
from dotenv import load_dotenv
|
||||
import copy
|
||||
|
||||
load_dotenv()
|
||||
sys.path.insert(
|
||||
0, os.path.abspath("../..")
|
||||
) # Adds the parent directory to the system path
|
||||
import asyncio
|
||||
from litellm import Router, Timeout
|
||||
import time
|
||||
from litellm.caching import Cache
|
||||
import litellm
|
||||
import openai
|
||||
|
||||
### Test just calling AsyncAzureOpenAI
|
||||
|
||||
openai_client = openai.AsyncAzureOpenAI(
|
||||
azure_endpoint=os.getenv("AZURE_API_BASE"),
|
||||
api_key=os.getenv("AZURE_API_KEY"),
|
||||
)
|
||||
|
||||
|
||||
async def call_acompletion(semaphore, input_data):
|
||||
async with semaphore:
|
||||
try:
|
||||
# Use asyncio.wait_for to set a timeout for the task
|
||||
response = await openai_client.chat.completions.create(**input_data)
|
||||
# Handle the response as needed
|
||||
print(response)
|
||||
return response
|
||||
except Timeout:
|
||||
print(f"Task timed out: {input_data}")
|
||||
return None # You may choose to return something else or raise an exception
|
||||
|
||||
|
||||
async def main():
|
||||
# Initialize the Router
|
||||
|
||||
# Create a semaphore with a capacity of 100
|
||||
semaphore = asyncio.Semaphore(100)
|
||||
|
||||
# List to hold all task references
|
||||
tasks = []
|
||||
start_time_all_tasks = time.time()
|
||||
# Launch 1000 tasks
|
||||
for _ in range(500):
|
||||
task = asyncio.create_task(
|
||||
call_acompletion(
|
||||
semaphore,
|
||||
{
|
||||
"model": "chatgpt-v-2",
|
||||
"messages": [{"role": "user", "content": "Hey, how's it going?"}],
|
||||
},
|
||||
)
|
||||
)
|
||||
tasks.append(task)
|
||||
|
||||
# Wait for all tasks to complete
|
||||
responses = await asyncio.gather(*tasks)
|
||||
# Process responses as needed
|
||||
# Record the end time for all tasks
|
||||
end_time_all_tasks = time.time()
|
||||
# Calculate the total time for all tasks
|
||||
total_time_all_tasks = end_time_all_tasks - start_time_all_tasks
|
||||
print(f"Total time for all tasks: {total_time_all_tasks} seconds")
|
||||
|
||||
# Calculate the average time per response
|
||||
average_time_per_response = total_time_all_tasks / len(responses)
|
||||
print(f"Average time per response: {average_time_per_response} seconds")
|
||||
print(f"NUMBER OF COMPLETED TASKS: {len(responses)}")
|
||||
|
||||
|
||||
# Run the main function
|
||||
asyncio.run(main())
|
||||
88
cookbook/litellm_router_load_test/test_loadtest_router.py
Normal file
88
cookbook/litellm_router_load_test/test_loadtest_router.py
Normal file
|
|
@ -0,0 +1,88 @@
|
|||
import sys, os
|
||||
import traceback
|
||||
from dotenv import load_dotenv
|
||||
import copy
|
||||
|
||||
load_dotenv()
|
||||
sys.path.insert(
|
||||
0, os.path.abspath("../..")
|
||||
) # Adds the parent directory to the system path
|
||||
import asyncio
|
||||
from litellm import Router, Timeout
|
||||
import time
|
||||
|
||||
### Test calling router async
|
||||
|
||||
|
||||
async def call_acompletion(semaphore, router: Router, input_data):
|
||||
async with semaphore:
|
||||
try:
|
||||
# Use asyncio.wait_for to set a timeout for the task
|
||||
response = await router.acompletion(**input_data)
|
||||
# Handle the response as needed
|
||||
print(response)
|
||||
return response
|
||||
except Timeout:
|
||||
print(f"Task timed out: {input_data}")
|
||||
return None # You may choose to return something else or raise an exception
|
||||
|
||||
|
||||
async def main():
|
||||
# Initialize the Router
|
||||
model_list = [
|
||||
{
|
||||
"model_name": "gpt-3.5-turbo",
|
||||
"litellm_params": {
|
||||
"model": "gpt-3.5-turbo",
|
||||
"api_key": os.getenv("OPENAI_API_KEY"),
|
||||
},
|
||||
},
|
||||
{
|
||||
"model_name": "gpt-3.5-turbo",
|
||||
"litellm_params": {
|
||||
"model": "azure/chatgpt-v-2",
|
||||
"api_key": os.getenv("AZURE_API_KEY"),
|
||||
"api_base": os.getenv("AZURE_API_BASE"),
|
||||
"api_version": os.getenv("AZURE_API_VERSION"),
|
||||
},
|
||||
},
|
||||
]
|
||||
router = Router(model_list=model_list, num_retries=3, timeout=10)
|
||||
|
||||
# Create a semaphore with a capacity of 100
|
||||
semaphore = asyncio.Semaphore(100)
|
||||
|
||||
# List to hold all task references
|
||||
tasks = []
|
||||
start_time_all_tasks = time.time()
|
||||
# Launch 1000 tasks
|
||||
for _ in range(500):
|
||||
task = asyncio.create_task(
|
||||
call_acompletion(
|
||||
semaphore,
|
||||
router,
|
||||
{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [{"role": "user", "content": "Hey, how's it going?"}],
|
||||
},
|
||||
)
|
||||
)
|
||||
tasks.append(task)
|
||||
|
||||
# Wait for all tasks to complete
|
||||
responses = await asyncio.gather(*tasks)
|
||||
# Process responses as needed
|
||||
# Record the end time for all tasks
|
||||
end_time_all_tasks = time.time()
|
||||
# Calculate the total time for all tasks
|
||||
total_time_all_tasks = end_time_all_tasks - start_time_all_tasks
|
||||
print(f"Total time for all tasks: {total_time_all_tasks} seconds")
|
||||
|
||||
# Calculate the average time per response
|
||||
average_time_per_response = total_time_all_tasks / len(responses)
|
||||
print(f"Average time per response: {average_time_per_response} seconds")
|
||||
print(f"NUMBER OF COMPLETED TASKS: {len(responses)}")
|
||||
|
||||
|
||||
# Run the main function
|
||||
asyncio.run(main())
|
||||
|
|
@ -0,0 +1,94 @@
|
|||
import sys, os
|
||||
import traceback
|
||||
from dotenv import load_dotenv
|
||||
import copy
|
||||
|
||||
load_dotenv()
|
||||
sys.path.insert(
|
||||
0, os.path.abspath("../..")
|
||||
) # Adds the parent directory to the system path
|
||||
import asyncio
|
||||
from litellm import Router, Timeout
|
||||
import time
|
||||
from litellm.caching import Cache
|
||||
import litellm
|
||||
|
||||
litellm.cache = Cache(
|
||||
type="s3", s3_bucket_name="cache-bucket-litellm", s3_region_name="us-west-2"
|
||||
)
|
||||
|
||||
### Test calling router with s3 Cache
|
||||
|
||||
|
||||
async def call_acompletion(semaphore, router: Router, input_data):
|
||||
async with semaphore:
|
||||
try:
|
||||
# Use asyncio.wait_for to set a timeout for the task
|
||||
response = await router.acompletion(**input_data)
|
||||
# Handle the response as needed
|
||||
print(response)
|
||||
return response
|
||||
except Timeout:
|
||||
print(f"Task timed out: {input_data}")
|
||||
return None # You may choose to return something else or raise an exception
|
||||
|
||||
|
||||
async def main():
|
||||
# Initialize the Router
|
||||
model_list = [
|
||||
{
|
||||
"model_name": "gpt-3.5-turbo",
|
||||
"litellm_params": {
|
||||
"model": "gpt-3.5-turbo",
|
||||
"api_key": os.getenv("OPENAI_API_KEY"),
|
||||
},
|
||||
},
|
||||
{
|
||||
"model_name": "gpt-3.5-turbo",
|
||||
"litellm_params": {
|
||||
"model": "azure/chatgpt-v-2",
|
||||
"api_key": os.getenv("AZURE_API_KEY"),
|
||||
"api_base": os.getenv("AZURE_API_BASE"),
|
||||
"api_version": os.getenv("AZURE_API_VERSION"),
|
||||
},
|
||||
},
|
||||
]
|
||||
router = Router(model_list=model_list, num_retries=3, timeout=10)
|
||||
|
||||
# Create a semaphore with a capacity of 100
|
||||
semaphore = asyncio.Semaphore(100)
|
||||
|
||||
# List to hold all task references
|
||||
tasks = []
|
||||
start_time_all_tasks = time.time()
|
||||
# Launch 1000 tasks
|
||||
for _ in range(500):
|
||||
task = asyncio.create_task(
|
||||
call_acompletion(
|
||||
semaphore,
|
||||
router,
|
||||
{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [{"role": "user", "content": "Hey, how's it going?"}],
|
||||
},
|
||||
)
|
||||
)
|
||||
tasks.append(task)
|
||||
|
||||
# Wait for all tasks to complete
|
||||
responses = await asyncio.gather(*tasks)
|
||||
# Process responses as needed
|
||||
# Record the end time for all tasks
|
||||
end_time_all_tasks = time.time()
|
||||
# Calculate the total time for all tasks
|
||||
total_time_all_tasks = end_time_all_tasks - start_time_all_tasks
|
||||
print(f"Total time for all tasks: {total_time_all_tasks} seconds")
|
||||
|
||||
# Calculate the average time per response
|
||||
average_time_per_response = total_time_all_tasks / len(responses)
|
||||
print(f"Average time per response: {average_time_per_response} seconds")
|
||||
print(f"NUMBER OF COMPLETED TASKS: {len(responses)}")
|
||||
|
||||
|
||||
# Run the main function
|
||||
asyncio.run(main())
|
||||
72
cookbook/misc/clickhouse.py
Normal file
72
cookbook/misc/clickhouse.py
Normal file
|
|
@ -0,0 +1,72 @@
|
|||
import clickhouse_connect
|
||||
import datetime as datetime
|
||||
import os
|
||||
|
||||
client = clickhouse_connect.get_client(
|
||||
host=os.getenv("CLICKHOUSE_HOST"),
|
||||
port=int(os.getenv("CLICKHOUSE_PORT")),
|
||||
username=os.getenv("CLICKHOUSE_USERNAME"),
|
||||
password=os.getenv("CLICKHOUSE_PASSWORD"),
|
||||
)
|
||||
import clickhouse_connect
|
||||
|
||||
row1 = [
|
||||
"ishaan", # request_id
|
||||
"GET", # call_type
|
||||
"api_key_123", # api_key
|
||||
50.00, # spend
|
||||
1000, # total_tokens
|
||||
800, # prompt_tokens
|
||||
200, # completion_tokens
|
||||
datetime.datetime.now(), # startTime (replace with the actual timestamp)
|
||||
datetime.datetime.now(), # endTime (replace with the actual timestamp)
|
||||
"gpt-3.5", # model
|
||||
"user123", # user
|
||||
'{"key": "value"}', # metadata (replace with valid JSON)
|
||||
"True", # cache_hit
|
||||
"cache_key_123", # cache_key
|
||||
"tag1,tag2", # request_tags
|
||||
]
|
||||
|
||||
row2 = [
|
||||
"jaffer", # request_id
|
||||
"POST", # call_type
|
||||
"api_key_456", # api_key
|
||||
30.50, # spend
|
||||
800, # total_tokens
|
||||
600, # prompt_tokens
|
||||
200, # completion_tokens
|
||||
datetime.datetime.now(), # startTime (replace with the actual timestamp)
|
||||
datetime.datetime.now(), # endTime (replace with the actual timestamp)
|
||||
"gpt-4.0", # model
|
||||
"user456", # user
|
||||
'{"key": "value"}', # metadata (replace with valid JSON)
|
||||
"False", # cache_hit
|
||||
"cache_key_789", # cache_key
|
||||
"tag3,tag4", # request_tags
|
||||
]
|
||||
|
||||
data = [row1, row2]
|
||||
resp = client.insert(
|
||||
"spend_logs",
|
||||
data,
|
||||
column_names=[
|
||||
"request_id",
|
||||
"call_type",
|
||||
"api_key",
|
||||
"spend",
|
||||
"total_tokens",
|
||||
"prompt_tokens",
|
||||
"completion_tokens",
|
||||
"startTime",
|
||||
"endTime",
|
||||
"model",
|
||||
"user",
|
||||
"metadata",
|
||||
"cache_hit",
|
||||
"cache_key",
|
||||
"request_tags",
|
||||
],
|
||||
)
|
||||
|
||||
print(resp)
|
||||
39
cookbook/misc/clickhouse_insert_logs.py
Normal file
39
cookbook/misc/clickhouse_insert_logs.py
Normal file
|
|
@ -0,0 +1,39 @@
|
|||
# insert data into clickhouse
|
||||
# response = client.command(
|
||||
# """
|
||||
# CREATE TEMPORARY TABLE temp_spend_logs AS (
|
||||
# SELECT
|
||||
# generateUUIDv4() AS request_id,
|
||||
# arrayElement(['TypeA', 'TypeB', 'TypeC'], rand() % 3 + 1) AS call_type,
|
||||
# 'ishaan' as api_key,
|
||||
# rand() * 1000 AS spend,
|
||||
# rand() * 100 AS total_tokens,
|
||||
# rand() * 50 AS prompt_tokens,
|
||||
# rand() * 50 AS completion_tokens,
|
||||
# toDate('2024-02-01') + toIntervalDay(rand()%27) AS startTime,
|
||||
# now() AS endTime,
|
||||
# arrayElement(['azure/gpt-4', 'gpt-3.5', 'vertexai/gemini-pro', 'mistral/mistral-small', 'ollama/llama2'], rand() % 3 + 1) AS model,
|
||||
# 'ishaan-insert-rand' as user,
|
||||
# 'data' as metadata,
|
||||
# 'true'AS cache_hit,
|
||||
# 'ishaan' as cache_key,
|
||||
# '{"tag1": "value1", "tag2": "value2"}' AS request_tags
|
||||
# FROM numbers(1, 1000000)
|
||||
# );
|
||||
# """
|
||||
# )
|
||||
|
||||
# client.command(
|
||||
# """
|
||||
# -- Insert data into spend_logs table
|
||||
# INSERT INTO spend_logs
|
||||
# SELECT * FROM temp_spend_logs;
|
||||
# """
|
||||
# )
|
||||
|
||||
|
||||
# client.command(
|
||||
# """
|
||||
# DROP TABLE IF EXISTS temp_spend_logs;
|
||||
# """
|
||||
# )
|
||||
2
cookbook/misc/dev_release.txt
Normal file
2
cookbook/misc/dev_release.txt
Normal file
|
|
@ -0,0 +1,2 @@
|
|||
python3 -m build
|
||||
twine upload --verbose dist/litellm-1.18.13.dev4.tar.gz -u __token__ -
|
||||
34
cookbook/misc/openai_timeouts.py
Normal file
34
cookbook/misc/openai_timeouts.py
Normal file
|
|
@ -0,0 +1,34 @@
|
|||
import os
|
||||
from openai import OpenAI
|
||||
from dotenv import load_dotenv
|
||||
import httpx
|
||||
import concurrent.futures
|
||||
|
||||
load_dotenv()
|
||||
|
||||
client = OpenAI(
|
||||
# This is the default and can be omitted
|
||||
api_key=os.environ.get("OPENAI_API_KEY"),
|
||||
)
|
||||
|
||||
|
||||
def create_chat_completion():
|
||||
return client.chat.completions.create(
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Say this is a test. Respond in 20 lines",
|
||||
}
|
||||
],
|
||||
model="gpt-3.5-turbo",
|
||||
)
|
||||
|
||||
|
||||
with concurrent.futures.ThreadPoolExecutor() as executor:
|
||||
# Set a timeout of 10 seconds
|
||||
future = executor.submit(create_chat_completion)
|
||||
try:
|
||||
chat_completion = future.result(timeout=0.00001)
|
||||
print(chat_completion)
|
||||
except concurrent.futures.TimeoutError:
|
||||
print("Operation timed out.")
|
||||
61
cookbook/misc/sagmaker_streaming.py
Normal file
61
cookbook/misc/sagmaker_streaming.py
Normal file
|
|
@ -0,0 +1,61 @@
|
|||
# Notes - on how to do sagemaker streaming using boto3
|
||||
import json
|
||||
import boto3
|
||||
|
||||
import sys, os
|
||||
import traceback
|
||||
from dotenv import load_dotenv
|
||||
|
||||
load_dotenv()
|
||||
import os, io
|
||||
|
||||
sys.path.insert(
|
||||
0, os.path.abspath("../..")
|
||||
) # Adds the parent directory to the system path
|
||||
import pytest
|
||||
import litellm
|
||||
|
||||
import io
|
||||
import json
|
||||
|
||||
|
||||
class TokenIterator:
|
||||
def __init__(self, stream):
|
||||
self.byte_iterator = iter(stream)
|
||||
self.buffer = io.BytesIO()
|
||||
self.read_pos = 0
|
||||
|
||||
def __iter__(self):
|
||||
return self
|
||||
|
||||
def __next__(self):
|
||||
while True:
|
||||
self.buffer.seek(self.read_pos)
|
||||
line = self.buffer.readline()
|
||||
if line and line[-1] == ord("\n"):
|
||||
self.read_pos += len(line) + 1
|
||||
full_line = line[:-1].decode("utf-8")
|
||||
line_data = json.loads(full_line.lstrip("data:").rstrip("/n"))
|
||||
return line_data["token"]["text"]
|
||||
chunk = next(self.byte_iterator)
|
||||
self.buffer.seek(0, io.SEEK_END)
|
||||
self.buffer.write(chunk["PayloadPart"]["Bytes"])
|
||||
|
||||
|
||||
payload = {
|
||||
"inputs": "How do I build a website?",
|
||||
"parameters": {"max_new_tokens": 256},
|
||||
"stream": True,
|
||||
}
|
||||
|
||||
import boto3
|
||||
|
||||
client = boto3.client("sagemaker-runtime", region_name="us-west-2")
|
||||
response = client.invoke_endpoint_with_response_stream(
|
||||
EndpointName="berri-benchmarking-Llama-2-70b-chat-hf-4",
|
||||
Body=json.dumps(payload),
|
||||
ContentType="application/json",
|
||||
)
|
||||
|
||||
# for token in TokenIterator(response["Body"]):
|
||||
# print(token)
|
||||
|
|
@ -33,7 +33,7 @@
|
|||
- Call all models using the OpenAI format - `completion(model, messages)`
|
||||
- Text responses will always be available at `['choices'][0]['message']['content']`
|
||||
- **Error Handling** Using Model Fallbacks (if `GPT-4` fails, try `llama2`)
|
||||
- **Logging** - Log Requests, Responses and Errors to `Supabase`, `Posthog`, `Mixpanel`, `Sentry`, `LLMonitor,` `Helicone` (Any of the supported providers here: https://litellm.readthedocs.io/en/latest/advanced/
|
||||
- **Logging** - Log Requests, Responses and Errors to `Supabase`, `Posthog`, `Mixpanel`, `Sentry`, `LLMonitor`,`Athina`, `Helicone` (Any of the supported providers here: https://litellm.readthedocs.io/en/latest/advanced/
|
||||
|
||||
**Example: Logs sent to Supabase**
|
||||
<img width="1015" alt="Screenshot 2023-08-11 at 4 02 46 PM" src="https://github.com/ishaan-jaff/proxy-server/assets/29436595/237557b8-ba09-4917-982c-8f3e1b2c8d08">
|
||||
|
|
|
|||
17
deploy/Dockerfile.ghcr_base
Normal file
17
deploy/Dockerfile.ghcr_base
Normal file
|
|
@ -0,0 +1,17 @@
|
|||
# Use the provided base image
|
||||
FROM ghcr.io/berriai/litellm:main-latest
|
||||
|
||||
# Set the working directory to /app
|
||||
WORKDIR /app
|
||||
|
||||
# Copy the configuration file into the container at /app
|
||||
COPY config.yaml .
|
||||
|
||||
# Make sure your entrypoint.sh is executable
|
||||
RUN chmod +x entrypoint.sh
|
||||
|
||||
# Expose the necessary port
|
||||
EXPOSE 4000/tcp
|
||||
|
||||
# Override the CMD instruction with your desired command and arguments
|
||||
CMD ["--port", "4000", "--config", "config.yaml", "--detailed_debug", "--run_gunicorn"]
|
||||
23
deploy/charts/litellm/.helmignore
Normal file
23
deploy/charts/litellm/.helmignore
Normal file
|
|
@ -0,0 +1,23 @@
|
|||
# Patterns to ignore when building packages.
|
||||
# This supports shell glob matching, relative path matching, and
|
||||
# negation (prefixed with !). Only one pattern per line.
|
||||
.DS_Store
|
||||
# Common VCS dirs
|
||||
.git/
|
||||
.gitignore
|
||||
.bzr/
|
||||
.bzrignore
|
||||
.hg/
|
||||
.hgignore
|
||||
.svn/
|
||||
# Common backup files
|
||||
*.swp
|
||||
*.bak
|
||||
*.tmp
|
||||
*.orig
|
||||
*~
|
||||
# Various IDEs
|
||||
.project
|
||||
.idea/
|
||||
*.tmproj
|
||||
.vscode/
|
||||
6
deploy/charts/litellm/Chart.lock
Normal file
6
deploy/charts/litellm/Chart.lock
Normal file
|
|
@ -0,0 +1,6 @@
|
|||
dependencies:
|
||||
- name: postgresql
|
||||
repository: oci://registry-1.docker.io/bitnamicharts
|
||||
version: 13.3.1
|
||||
digest: sha256:f5c129150f0d38dd06752ab37f3c8e143d7c14d30379af058767bcd9f4ba83dd
|
||||
generated: "2024-01-19T11:32:56.694808861+11:00"
|
||||
33
deploy/charts/litellm/Chart.yaml
Normal file
33
deploy/charts/litellm/Chart.yaml
Normal file
|
|
@ -0,0 +1,33 @@
|
|||
apiVersion: v2
|
||||
|
||||
# We can't call ourselves just "litellm" because then we couldn't publish to the
|
||||
# same OCI repository as the "litellm" OCI image
|
||||
name: litellm
|
||||
description: Call all LLM APIs using the OpenAI format
|
||||
|
||||
# A chart can be either an 'application' or a 'library' chart.
|
||||
#
|
||||
# Application charts are a collection of templates that can be packaged into versioned archives
|
||||
# to be deployed.
|
||||
#
|
||||
# Library charts provide useful utilities or functions for the chart developer. They're included as
|
||||
# a dependency of application charts to inject those utilities and functions into the rendering
|
||||
# pipeline. Library charts do not define any templates and therefore cannot be deployed.
|
||||
type: application
|
||||
|
||||
# This is the chart version. This version number should be incremented each time you make changes
|
||||
# to the chart and its templates, including the app version.
|
||||
# Versions are expected to follow Semantic Versioning (https://semver.org/)
|
||||
version: 0.2.0
|
||||
|
||||
# This is the version number of the application being deployed. This version number should be
|
||||
# incremented each time you make changes to the application. Versions are not expected to
|
||||
# follow Semantic Versioning. They should reflect the version the application is using.
|
||||
# It is recommended to use it with quotes.
|
||||
appVersion: v1.24.5
|
||||
|
||||
dependencies:
|
||||
- name: "postgresql"
|
||||
version: ">=13.3.0"
|
||||
repository: oci://registry-1.docker.io/bitnamicharts
|
||||
condition: db.deployStandalone
|
||||
93
deploy/charts/litellm/README.md
Normal file
93
deploy/charts/litellm/README.md
Normal file
|
|
@ -0,0 +1,93 @@
|
|||
# Helm Chart for LiteLLM
|
||||
|
||||
## Prerequisites
|
||||
|
||||
- Kubernetes 1.23+
|
||||
- Helm 3.8.0+
|
||||
|
||||
If `db.deployStandalone` is used:
|
||||
- PV provisioner support in the underlying infrastructure
|
||||
|
||||
If `db.useStackgresOperator` is used (not yet implemented):
|
||||
- The Stackgres Operator must already be installed in the Kubernetes Cluster. This chart will **not** install the operator if it is missing.
|
||||
|
||||
## Parameters
|
||||
|
||||
### LiteLLM Proxy Deployment Settings
|
||||
|
||||
| Name | Description | Value |
|
||||
| ---------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----- |
|
||||
| `replicaCount` | The number of LiteLLM Proxy pods to be deployed | `1` |
|
||||
| `masterkey` | The Master API Key for LiteLLM. If not specified, a random key is generated. | N/A |
|
||||
| `environmentSecrets` | An optional array of Secret object names. The keys and values in these secrets will be presented to the LiteLLM proxy pod as environment variables. See below for an example Secret object. | `[]` |
|
||||
| `image.repository` | LiteLLM Proxy image repository | `ghcr.io/berriai/litellm` |
|
||||
| `image.pullPolicy` | LiteLLM Proxy image pull policy | `IfNotPresent` |
|
||||
| `image.tag` | Overrides the image tag whose default the latest version of LiteLLM at the time this chart was published. | `""` |
|
||||
| `image.dbReadyImage` | On Pod startup, an initContainer is used to make sure the Postgres database is available before attempting to start LiteLLM. This field specifies the image to use as that initContainer. | `docker.io/bitnami/postgresql` |
|
||||
| `image.dbReadyTag` | Tag for the above image. If not specified, "latest" is used. | `""` |
|
||||
| `imagePullSecrets` | Registry credentials for the LiteLLM and initContainer images. | `[]` |
|
||||
| `serviceAccount.create` | Whether or not to create a Kubernetes Service Account for this deployment. The default is `false` because LiteLLM has no need to access the Kubernetes API. | `false` |
|
||||
| `service.type` | Kubernetes Service type (e.g. `LoadBalancer`, `ClusterIP`, etc.) | `ClusterIP` |
|
||||
| `service.port` | TCP port that the Kubernetes Service will listen on. Also the TCP port within the Pod that the proxy will listen on. | `8000` |
|
||||
| `ingress.*` | See [values.yaml](./values.yaml) for example settings | N/A |
|
||||
| `proxy_config.*` | See [values.yaml](./values.yaml) for default settings. See [example_config_yaml](../../../litellm/proxy/example_config_yaml/) for configuration examples. | N/A |
|
||||
|
||||
#### Example `environmentSecrets` Secret
|
||||
```
|
||||
apiVersion: v1
|
||||
kind: Secret
|
||||
metadata:
|
||||
name: litellm-envsecrets
|
||||
data:
|
||||
AZURE_OPENAI_API_KEY: TXlTZWN1cmVLM3k=
|
||||
type: Opaque
|
||||
```
|
||||
|
||||
### Database Settings
|
||||
| Name | Description | Value |
|
||||
| ---------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----- |
|
||||
| `db.useExisting` | Use an existing Postgres database. A Kubernetes Secret object must exist that contains credentials for connecting to the database. An example secret object definition is provided below. | `false` |
|
||||
| `db.endpoint` | If `db.useExisting` is `true`, this is the IP, Hostname or Service Name of the Postgres server to connect to. | `localhost` |
|
||||
| `db.database` | If `db.useExisting` is `true`, the name of the existing database to connect to. | `litellm` |
|
||||
| `db.secret.name` | If `db.useExisting` is `true`, the name of the Kubernetes Secret that contains credentials. | `postgres` |
|
||||
| `db.secret.usernameKey` | If `db.useExisting` is `true`, the name of the key within the Kubernetes Secret that holds the username for authenticating with the Postgres instance. | `username` |
|
||||
| `db.secret.passwordKey` | If `db.useExisting` is `true`, the name of the key within the Kubernetes Secret that holds the password associates with the above user. | `password` |
|
||||
| `db.useStackgresOperator` | Not yet implemented. | `false` |
|
||||
| `db.deployStandalone` | Deploy a standalone, single instance deployment of Postgres, using the Bitnami postgresql chart. This is useful for getting started but doesn't provide HA or (by default) data backups. | `true` |
|
||||
| `postgresql.*` | If `db.deployStandalone` is `true`, configuration passed to the Bitnami postgresql chart. See the [Bitnami Documentation](https://github.com/bitnami/charts/tree/main/bitnami/postgresql) for full configuration details. See [values.yaml](./values.yaml) for the default configuration. | See [values.yaml](./values.yaml) |
|
||||
| `postgresql.auth.*` | If `db.deployStandalone` is `true`, care should be taken to ensure the default `password` and `postgres-password` values are **NOT** used. | `NoTaGrEaTpAsSwOrD` |
|
||||
|
||||
#### Example Postgres `db.useExisting` Secret
|
||||
```yaml
|
||||
apiVersion: v1
|
||||
kind: Secret
|
||||
metadata:
|
||||
name: postgres
|
||||
data:
|
||||
# Password for the "postgres" user
|
||||
postgres-password: <some secure password, base64 encoded>
|
||||
username: litellm
|
||||
password: <some secure password, base64 encoded>
|
||||
type: Opaque
|
||||
```
|
||||
|
||||
## Accessing the Admin UI
|
||||
When browsing to the URL published per the settings in `ingress.*`, you will
|
||||
be prompted for **Admin Configuration**. The **Proxy Endpoint** is the internal
|
||||
(from the `litellm` pod's perspective) URL published by the `<RELEASE>-litellm`
|
||||
Kubernetes Service. If the deployment uses the default settings for this
|
||||
service, the **Proxy Endpoint** should be set to `http://<RELEASE>-litellm:8000`.
|
||||
|
||||
The **Proxy Key** is the value specified for `masterkey` or, if a `masterkey`
|
||||
was not provided to the helm command line, the `masterkey` is a randomly
|
||||
generated string stored in the `<RELEASE>-litellm-masterkey` Kubernetes Secret.
|
||||
|
||||
```bash
|
||||
kubectl -n litellm get secret <RELEASE>-litellm-masterkey -o jsonpath="{.data.masterkey}"
|
||||
```
|
||||
|
||||
## Admin UI Limitations
|
||||
At the time of writing, the Admin UI is unable to add models. This is because
|
||||
it would need to update the `config.yaml` file which is a exposed ConfigMap, and
|
||||
therefore, read-only. This is a limitation of this helm chart, not the Admin UI
|
||||
itself.
|
||||
22
deploy/charts/litellm/templates/NOTES.txt
Normal file
22
deploy/charts/litellm/templates/NOTES.txt
Normal file
|
|
@ -0,0 +1,22 @@
|
|||
1. Get the application URL by running these commands:
|
||||
{{- if .Values.ingress.enabled }}
|
||||
{{- range $host := .Values.ingress.hosts }}
|
||||
{{- range .paths }}
|
||||
http{{ if $.Values.ingress.tls }}s{{ end }}://{{ $host.host }}{{ .path }}
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
{{- else if contains "NodePort" .Values.service.type }}
|
||||
export NODE_PORT=$(kubectl get --namespace {{ .Release.Namespace }} -o jsonpath="{.spec.ports[0].nodePort}" services {{ include "litellm.fullname" . }})
|
||||
export NODE_IP=$(kubectl get nodes --namespace {{ .Release.Namespace }} -o jsonpath="{.items[0].status.addresses[0].address}")
|
||||
echo http://$NODE_IP:$NODE_PORT
|
||||
{{- else if contains "LoadBalancer" .Values.service.type }}
|
||||
NOTE: It may take a few minutes for the LoadBalancer IP to be available.
|
||||
You can watch the status of by running 'kubectl get --namespace {{ .Release.Namespace }} svc -w {{ include "litellm.fullname" . }}'
|
||||
export SERVICE_IP=$(kubectl get svc --namespace {{ .Release.Namespace }} {{ include "litellm.fullname" . }} --template "{{"{{ range (index .status.loadBalancer.ingress 0) }}{{.}}{{ end }}"}}")
|
||||
echo http://$SERVICE_IP:{{ .Values.service.port }}
|
||||
{{- else if contains "ClusterIP" .Values.service.type }}
|
||||
export POD_NAME=$(kubectl get pods --namespace {{ .Release.Namespace }} -l "app.kubernetes.io/name={{ include "litellm.name" . }},app.kubernetes.io/instance={{ .Release.Name }}" -o jsonpath="{.items[0].metadata.name}")
|
||||
export CONTAINER_PORT=$(kubectl get pod --namespace {{ .Release.Namespace }} $POD_NAME -o jsonpath="{.spec.containers[0].ports[0].containerPort}")
|
||||
echo "Visit http://127.0.0.1:8080 to use your application"
|
||||
kubectl --namespace {{ .Release.Namespace }} port-forward $POD_NAME 8080:$CONTAINER_PORT
|
||||
{{- end }}
|
||||
62
deploy/charts/litellm/templates/_helpers.tpl
Normal file
62
deploy/charts/litellm/templates/_helpers.tpl
Normal file
|
|
@ -0,0 +1,62 @@
|
|||
{{/*
|
||||
Expand the name of the chart.
|
||||
*/}}
|
||||
{{- define "litellm.name" -}}
|
||||
{{- default .Chart.Name .Values.nameOverride | trunc 63 | trimSuffix "-" }}
|
||||
{{- end }}
|
||||
|
||||
{{/*
|
||||
Create a default fully qualified app name.
|
||||
We truncate at 63 chars because some Kubernetes name fields are limited to this (by the DNS naming spec).
|
||||
If release name contains chart name it will be used as a full name.
|
||||
*/}}
|
||||
{{- define "litellm.fullname" -}}
|
||||
{{- if .Values.fullnameOverride }}
|
||||
{{- .Values.fullnameOverride | trunc 63 | trimSuffix "-" }}
|
||||
{{- else }}
|
||||
{{- $name := default .Chart.Name .Values.nameOverride }}
|
||||
{{- if contains $name .Release.Name }}
|
||||
{{- .Release.Name | trunc 63 | trimSuffix "-" }}
|
||||
{{- else }}
|
||||
{{- printf "%s-%s" .Release.Name $name | trunc 63 | trimSuffix "-" }}
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
|
||||
{{/*
|
||||
Create chart name and version as used by the chart label.
|
||||
*/}}
|
||||
{{- define "litellm.chart" -}}
|
||||
{{- printf "%s-%s" .Chart.Name .Chart.Version | replace "+" "_" | trunc 63 | trimSuffix "-" }}
|
||||
{{- end }}
|
||||
|
||||
{{/*
|
||||
Common labels
|
||||
*/}}
|
||||
{{- define "litellm.labels" -}}
|
||||
helm.sh/chart: {{ include "litellm.chart" . }}
|
||||
{{ include "litellm.selectorLabels" . }}
|
||||
{{- if .Chart.AppVersion }}
|
||||
app.kubernetes.io/version: {{ .Chart.AppVersion | quote }}
|
||||
{{- end }}
|
||||
app.kubernetes.io/managed-by: {{ .Release.Service }}
|
||||
{{- end }}
|
||||
|
||||
{{/*
|
||||
Selector labels
|
||||
*/}}
|
||||
{{- define "litellm.selectorLabels" -}}
|
||||
app.kubernetes.io/name: {{ include "litellm.name" . }}
|
||||
app.kubernetes.io/instance: {{ .Release.Name }}
|
||||
{{- end }}
|
||||
|
||||
{{/*
|
||||
Create the name of the service account to use
|
||||
*/}}
|
||||
{{- define "litellm.serviceAccountName" -}}
|
||||
{{- if .Values.serviceAccount.create }}
|
||||
{{- default (include "litellm.fullname" .) .Values.serviceAccount.name }}
|
||||
{{- else }}
|
||||
{{- default "default" .Values.serviceAccount.name }}
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
7
deploy/charts/litellm/templates/configmap-litellm.yaml
Normal file
7
deploy/charts/litellm/templates/configmap-litellm.yaml
Normal file
|
|
@ -0,0 +1,7 @@
|
|||
apiVersion: v1
|
||||
kind: ConfigMap
|
||||
metadata:
|
||||
name: {{ include "litellm.fullname" . }}-config
|
||||
data:
|
||||
config.yaml: |
|
||||
{{ .Values.proxy_config | toYaml | indent 6 }}
|
||||
221
deploy/charts/litellm/templates/deployment.yaml
Normal file
221
deploy/charts/litellm/templates/deployment.yaml
Normal file
|
|
@ -0,0 +1,221 @@
|
|||
apiVersion: apps/v1
|
||||
kind: Deployment
|
||||
metadata:
|
||||
name: {{ include "litellm.fullname" . }}
|
||||
labels:
|
||||
{{- include "litellm.labels" . | nindent 4 }}
|
||||
spec:
|
||||
{{- if not .Values.autoscaling.enabled }}
|
||||
replicas: {{ .Values.replicaCount }}
|
||||
{{- end }}
|
||||
selector:
|
||||
matchLabels:
|
||||
{{- include "litellm.selectorLabels" . | nindent 6 }}
|
||||
template:
|
||||
metadata:
|
||||
{{- with .Values.podAnnotations }}
|
||||
annotations:
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- end }}
|
||||
labels:
|
||||
{{- include "litellm.labels" . | nindent 8 }}
|
||||
{{- with .Values.podLabels }}
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- end }}
|
||||
spec:
|
||||
{{- with .Values.imagePullSecrets }}
|
||||
imagePullSecrets:
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- end }}
|
||||
serviceAccountName: {{ include "litellm.serviceAccountName" . }}
|
||||
securityContext:
|
||||
{{- toYaml .Values.podSecurityContext | nindent 8 }}
|
||||
initContainers:
|
||||
- name: db-ready
|
||||
securityContext:
|
||||
{{- toYaml .Values.securityContext | nindent 12 }}
|
||||
image: "docker.io/bitnami/postgresql:16.1.0-debian-11-r20"
|
||||
imagePullPolicy: {{ .Values.image.pullPolicy }}
|
||||
env:
|
||||
{{- if .Values.db.deployStandalone }}
|
||||
- name: DATABASE_USERNAME
|
||||
valueFrom:
|
||||
secretKeyRef:
|
||||
name: {{ include "litellm.fullname" . }}-dbcredentials
|
||||
key: username
|
||||
- name: PGPASSWORD
|
||||
valueFrom:
|
||||
secretKeyRef:
|
||||
name: {{ include "litellm.fullname" . }}-dbcredentials
|
||||
key: password
|
||||
- name: DATABASE_HOST
|
||||
value: {{ .Release.Name }}-postgresql
|
||||
- name: DATABASE_NAME
|
||||
value: litellm
|
||||
{{- else if .Values.db.useExisting }}
|
||||
- name: DATABASE_USERNAME
|
||||
valueFrom:
|
||||
secretKeyRef:
|
||||
name: {{ .Values.db.secret.name }}
|
||||
key: {{ .Values.db.secret.usernameKey }}
|
||||
- name: PGPASSWORD
|
||||
valueFrom:
|
||||
secretKeyRef:
|
||||
name: {{ .Values.db.secret.name }}
|
||||
key: {{ .Values.db.secret.passwordKey }}
|
||||
- name: DATABASE_HOST
|
||||
value: {{ .Values.db.endpoint }}
|
||||
- name: DATABASE_NAME
|
||||
value: litellm
|
||||
{{- end }}
|
||||
command:
|
||||
- sh
|
||||
- -c
|
||||
- |
|
||||
# Maximum wait time will be (limit * 2) seconds.
|
||||
limit=60
|
||||
current=0
|
||||
ret=1
|
||||
while [ $current -lt $limit ] && [ $ret -ne 0 ]; do
|
||||
echo "Waiting for database to be ready $current"
|
||||
psql -U $(DATABASE_USERNAME) -h $(DATABASE_HOST) -l
|
||||
ret=$?
|
||||
current=$(( $current + 1 ))
|
||||
sleep 2
|
||||
done
|
||||
if [ $ret -eq 0 ]; then
|
||||
echo "Database is ready"
|
||||
else
|
||||
echo "Database failed to become ready before we gave up waiting."
|
||||
fi
|
||||
{{ if .Values.securityContext.readOnlyRootFilesystem }}
|
||||
volumeMounts:
|
||||
- name: tmp
|
||||
mountPath: /tmp
|
||||
{{ end }}
|
||||
containers:
|
||||
- name: {{ include "litellm.name" . }}
|
||||
securityContext:
|
||||
{{- toYaml .Values.securityContext | nindent 12 }}
|
||||
image: "{{ .Values.image.repository }}:{{ .Values.image.tag | default (printf "main-%s" .Chart.AppVersion) }}"
|
||||
imagePullPolicy: {{ .Values.image.pullPolicy }}
|
||||
env:
|
||||
- name: HOST
|
||||
value: "0.0.0.0"
|
||||
- name: PORT
|
||||
value: {{ .Values.service.port | quote}}
|
||||
{{- if .Values.db.deployStandalone }}
|
||||
- name: DATABASE_USERNAME
|
||||
valueFrom:
|
||||
secretKeyRef:
|
||||
name: {{ include "litellm.fullname" . }}-dbcredentials
|
||||
key: username
|
||||
- name: DATABASE_PASSWORD
|
||||
valueFrom:
|
||||
secretKeyRef:
|
||||
name: {{ include "litellm.fullname" . }}-dbcredentials
|
||||
key: password
|
||||
- name: DATABASE_HOST
|
||||
value: {{ .Release.Name }}-postgresql
|
||||
- name: DATABASE_NAME
|
||||
value: litellm
|
||||
{{- else if .Values.db.useExisting }}
|
||||
- name: DATABASE_USERNAME
|
||||
valueFrom:
|
||||
secretKeyRef:
|
||||
name: {{ .Values.db.secret.name }}
|
||||
key: {{ .Values.db.secret.usernameKey }}
|
||||
- name: DATABASE_PASSWORD
|
||||
valueFrom:
|
||||
secretKeyRef:
|
||||
name: {{ .Values.db.secret.name }}
|
||||
key: {{ .Values.db.secret.passwordKey }}
|
||||
- name: DATABASE_HOST
|
||||
value: {{ .Values.db.endpoint }}
|
||||
- name: DATABASE_NAME
|
||||
value: {{ .Values.db.database }}
|
||||
{{- end }}
|
||||
- name: DATABASE_URL
|
||||
value: "postgresql://$(DATABASE_USERNAME):$(DATABASE_PASSWORD)@$(DATABASE_HOST)/$(DATABASE_NAME)"
|
||||
- name: PROXY_MASTER_KEY
|
||||
valueFrom:
|
||||
secretKeyRef:
|
||||
name: {{ include "litellm.fullname" . }}-masterkey
|
||||
key: masterkey
|
||||
envFrom:
|
||||
{{- range .Values.environmentSecrets }}
|
||||
- secretRef:
|
||||
name: {{ . }}
|
||||
{{- end }}
|
||||
args:
|
||||
- --config
|
||||
- /etc/litellm/config.yaml
|
||||
- --run_gunicorn
|
||||
ports:
|
||||
- name: http
|
||||
containerPort: {{ .Values.service.port }}
|
||||
protocol: TCP
|
||||
livenessProbe:
|
||||
httpGet:
|
||||
path: /health/liveliness
|
||||
port: http
|
||||
readinessProbe:
|
||||
httpGet:
|
||||
path: /health/readiness
|
||||
port: http
|
||||
# Give the container time to start up. Up to 5 minutes (10 * 30 seconds)
|
||||
startupProbe:
|
||||
httpGet:
|
||||
path: /health/readiness
|
||||
port: http
|
||||
failureThreshold: 30
|
||||
periodSeconds: 10
|
||||
resources:
|
||||
{{- toYaml .Values.resources | nindent 12 }}
|
||||
volumeMounts:
|
||||
- name: litellm-config
|
||||
mountPath: /etc/litellm/
|
||||
{{ if .Values.securityContext.readOnlyRootFilesystem }}
|
||||
- name: tmp
|
||||
mountPath: /tmp
|
||||
- name: cache
|
||||
mountPath: /.cache
|
||||
- name: npm
|
||||
mountPath: /.npm
|
||||
{{- end }}
|
||||
{{- with .Values.volumeMounts }}
|
||||
{{- toYaml . | nindent 12 }}
|
||||
{{- end }}
|
||||
volumes:
|
||||
{{ if .Values.securityContext.readOnlyRootFilesystem }}
|
||||
- name: tmp
|
||||
emptyDir:
|
||||
sizeLimit: 500Mi
|
||||
- name: cache
|
||||
emptyDir:
|
||||
sizeLimit: 500Mi
|
||||
- name: npm
|
||||
emptyDir:
|
||||
sizeLimit: 500Mi
|
||||
{{- end }}
|
||||
- name: litellm-config
|
||||
configMap:
|
||||
name: {{ include "litellm.fullname" . }}-config
|
||||
items:
|
||||
- key: "config.yaml"
|
||||
path: "config.yaml"
|
||||
{{- with .Values.volumes }}
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- end }}
|
||||
{{- with .Values.nodeSelector }}
|
||||
nodeSelector:
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- end }}
|
||||
{{- with .Values.affinity }}
|
||||
affinity:
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- end }}
|
||||
{{- with .Values.tolerations }}
|
||||
tolerations:
|
||||
{{- toYaml . | nindent 8 }}
|
||||
{{- end }}
|
||||
32
deploy/charts/litellm/templates/hpa.yaml
Normal file
32
deploy/charts/litellm/templates/hpa.yaml
Normal file
|
|
@ -0,0 +1,32 @@
|
|||
{{- if .Values.autoscaling.enabled }}
|
||||
apiVersion: autoscaling/v2
|
||||
kind: HorizontalPodAutoscaler
|
||||
metadata:
|
||||
name: {{ include "litellm.fullname" . }}
|
||||
labels:
|
||||
{{- include "litellm.labels" . | nindent 4 }}
|
||||
spec:
|
||||
scaleTargetRef:
|
||||
apiVersion: apps/v1
|
||||
kind: Deployment
|
||||
name: {{ include "litellm.fullname" . }}
|
||||
minReplicas: {{ .Values.autoscaling.minReplicas }}
|
||||
maxReplicas: {{ .Values.autoscaling.maxReplicas }}
|
||||
metrics:
|
||||
{{- if .Values.autoscaling.targetCPUUtilizationPercentage }}
|
||||
- type: Resource
|
||||
resource:
|
||||
name: cpu
|
||||
target:
|
||||
type: Utilization
|
||||
averageUtilization: {{ .Values.autoscaling.targetCPUUtilizationPercentage }}
|
||||
{{- end }}
|
||||
{{- if .Values.autoscaling.targetMemoryUtilizationPercentage }}
|
||||
- type: Resource
|
||||
resource:
|
||||
name: memory
|
||||
target:
|
||||
type: Utilization
|
||||
averageUtilization: {{ .Values.autoscaling.targetMemoryUtilizationPercentage }}
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
61
deploy/charts/litellm/templates/ingress.yaml
Normal file
61
deploy/charts/litellm/templates/ingress.yaml
Normal file
|
|
@ -0,0 +1,61 @@
|
|||
{{- if .Values.ingress.enabled -}}
|
||||
{{- $fullName := include "litellm.fullname" . -}}
|
||||
{{- $svcPort := .Values.service.port -}}
|
||||
{{- if and .Values.ingress.className (not (semverCompare ">=1.18-0" .Capabilities.KubeVersion.GitVersion)) }}
|
||||
{{- if not (hasKey .Values.ingress.annotations "kubernetes.io/ingress.class") }}
|
||||
{{- $_ := set .Values.ingress.annotations "kubernetes.io/ingress.class" .Values.ingress.className}}
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
{{- if semverCompare ">=1.19-0" .Capabilities.KubeVersion.GitVersion -}}
|
||||
apiVersion: networking.k8s.io/v1
|
||||
{{- else if semverCompare ">=1.14-0" .Capabilities.KubeVersion.GitVersion -}}
|
||||
apiVersion: networking.k8s.io/v1beta1
|
||||
{{- else -}}
|
||||
apiVersion: extensions/v1beta1
|
||||
{{- end }}
|
||||
kind: Ingress
|
||||
metadata:
|
||||
name: {{ $fullName }}
|
||||
labels:
|
||||
{{- include "litellm.labels" . | nindent 4 }}
|
||||
{{- with .Values.ingress.annotations }}
|
||||
annotations:
|
||||
{{- toYaml . | nindent 4 }}
|
||||
{{- end }}
|
||||
spec:
|
||||
{{- if and .Values.ingress.className (semverCompare ">=1.18-0" .Capabilities.KubeVersion.GitVersion) }}
|
||||
ingressClassName: {{ .Values.ingress.className }}
|
||||
{{- end }}
|
||||
{{- if .Values.ingress.tls }}
|
||||
tls:
|
||||
{{- range .Values.ingress.tls }}
|
||||
- hosts:
|
||||
{{- range .hosts }}
|
||||
- {{ . | quote }}
|
||||
{{- end }}
|
||||
secretName: {{ .secretName }}
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
rules:
|
||||
{{- range .Values.ingress.hosts }}
|
||||
- host: {{ .host | quote }}
|
||||
http:
|
||||
paths:
|
||||
{{- range .paths }}
|
||||
- path: {{ .path }}
|
||||
{{- if and .pathType (semverCompare ">=1.18-0" $.Capabilities.KubeVersion.GitVersion) }}
|
||||
pathType: {{ .pathType }}
|
||||
{{- end }}
|
||||
backend:
|
||||
{{- if semverCompare ">=1.19-0" $.Capabilities.KubeVersion.GitVersion }}
|
||||
service:
|
||||
name: {{ $fullName }}
|
||||
port:
|
||||
number: {{ $svcPort }}
|
||||
{{- else }}
|
||||
serviceName: {{ $fullName }}
|
||||
servicePort: {{ $svcPort }}
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
{{- end }}
|
||||
12
deploy/charts/litellm/templates/secret-dbcredentials.yaml
Normal file
12
deploy/charts/litellm/templates/secret-dbcredentials.yaml
Normal file
|
|
@ -0,0 +1,12 @@
|
|||
{{- if .Values.db.deployStandalone -}}
|
||||
apiVersion: v1
|
||||
kind: Secret
|
||||
metadata:
|
||||
name: {{ include "litellm.fullname" . }}-dbcredentials
|
||||
data:
|
||||
# Password for the "postgres" user
|
||||
postgres-password: {{ ( index .Values.postgresql.auth "postgres-password") | default "litellm" | b64enc }}
|
||||
username: {{ .Values.postgresql.auth.username | default "litellm" | b64enc }}
|
||||
password: {{ .Values.postgresql.auth.password | default "litellm" | b64enc }}
|
||||
type: Opaque
|
||||
{{- end -}}
|
||||
8
deploy/charts/litellm/templates/secret-masterkey.yaml
Normal file
8
deploy/charts/litellm/templates/secret-masterkey.yaml
Normal file
|
|
@ -0,0 +1,8 @@
|
|||
{{ $masterkey := (.Values.masterkey | default (randAlphaNum 17)) }}
|
||||
apiVersion: v1
|
||||
kind: Secret
|
||||
metadata:
|
||||
name: {{ include "litellm.fullname" . }}-masterkey
|
||||
data:
|
||||
masterkey: {{ $masterkey | b64enc }}
|
||||
type: Opaque
|
||||
15
deploy/charts/litellm/templates/service.yaml
Normal file
15
deploy/charts/litellm/templates/service.yaml
Normal file
|
|
@ -0,0 +1,15 @@
|
|||
apiVersion: v1
|
||||
kind: Service
|
||||
metadata:
|
||||
name: {{ include "litellm.fullname" . }}
|
||||
labels:
|
||||
{{- include "litellm.labels" . | nindent 4 }}
|
||||
spec:
|
||||
type: {{ .Values.service.type }}
|
||||
ports:
|
||||
- port: {{ .Values.service.port }}
|
||||
targetPort: http
|
||||
protocol: TCP
|
||||
name: http
|
||||
selector:
|
||||
{{- include "litellm.selectorLabels" . | nindent 4 }}
|
||||
13
deploy/charts/litellm/templates/serviceaccount.yaml
Normal file
13
deploy/charts/litellm/templates/serviceaccount.yaml
Normal file
|
|
@ -0,0 +1,13 @@
|
|||
{{- if .Values.serviceAccount.create -}}
|
||||
apiVersion: v1
|
||||
kind: ServiceAccount
|
||||
metadata:
|
||||
name: {{ include "litellm.serviceAccountName" . }}
|
||||
labels:
|
||||
{{- include "litellm.labels" . | nindent 4 }}
|
||||
{{- with .Values.serviceAccount.annotations }}
|
||||
annotations:
|
||||
{{- toYaml . | nindent 4 }}
|
||||
{{- end }}
|
||||
automountServiceAccountToken: {{ .Values.serviceAccount.automount }}
|
||||
{{- end }}
|
||||
15
deploy/charts/litellm/templates/tests/test-connection.yaml
Normal file
15
deploy/charts/litellm/templates/tests/test-connection.yaml
Normal file
|
|
@ -0,0 +1,15 @@
|
|||
apiVersion: v1
|
||||
kind: Pod
|
||||
metadata:
|
||||
name: "{{ include "litellm.fullname" . }}-test-connection"
|
||||
labels:
|
||||
{{- include "litellm.labels" . | nindent 4 }}
|
||||
annotations:
|
||||
"helm.sh/hook": test
|
||||
spec:
|
||||
containers:
|
||||
- name: wget
|
||||
image: busybox
|
||||
command: ['wget']
|
||||
args: ['{{ include "litellm.fullname" . }}:{{ .Values.service.port }}/health/readiness']
|
||||
restartPolicy: Never
|
||||
168
deploy/charts/litellm/values.yaml
Normal file
168
deploy/charts/litellm/values.yaml
Normal file
|
|
@ -0,0 +1,168 @@
|
|||
# Default values for litellm.
|
||||
# This is a YAML-formatted file.
|
||||
# Declare variables to be passed into your templates.
|
||||
|
||||
replicaCount: 1
|
||||
|
||||
image:
|
||||
# Use "ghcr.io/berriai/litellm-database" for optimized image with database
|
||||
# Alternatively, use "ghcr.io/berriai/litellm" for the default image
|
||||
repository: ghcr.io/berriai/litellm-database
|
||||
pullPolicy: IfNotPresent
|
||||
# Overrides the image tag whose default is the chart appVersion.
|
||||
# tag: "main-latest"
|
||||
tag: ""
|
||||
|
||||
# Image and tag used for the init container to check and wait for the
|
||||
# readiness of the postgres database.
|
||||
dbReadyImage: docker.io/bitnami/postgresql
|
||||
dbReadyTag: ""
|
||||
|
||||
imagePullSecrets: []
|
||||
nameOverride: "litellm"
|
||||
fullnameOverride: ""
|
||||
|
||||
serviceAccount:
|
||||
# Specifies whether a service account should be created
|
||||
create: false
|
||||
# Automatically mount a ServiceAccount's API credentials?
|
||||
automount: true
|
||||
# Annotations to add to the service account
|
||||
annotations: {}
|
||||
# The name of the service account to use.
|
||||
# If not set and create is true, a name is generated using the fullname template
|
||||
name: ""
|
||||
|
||||
podAnnotations: {}
|
||||
podLabels: {}
|
||||
|
||||
# At the time of writing, the litellm docker image requires write access to the
|
||||
# filesystem on startup so that prisma can install some dependencies.
|
||||
podSecurityContext: {}
|
||||
securityContext: {}
|
||||
# capabilities:
|
||||
# drop:
|
||||
# - ALL
|
||||
# readOnlyRootFilesystem: false
|
||||
# runAsNonRoot: true
|
||||
# runAsUser: 1000
|
||||
|
||||
# A list of Kubernetes Secret objects that will be exported to the LiteLLM proxy
|
||||
# pod as environment variables. These secrets can then be referenced in the
|
||||
# configuration file (or "litellm" ConfigMap) with `os.environ/<Env Var Name>`
|
||||
environmentSecrets: []
|
||||
# - litellm-envsecrets
|
||||
|
||||
service:
|
||||
type: ClusterIP
|
||||
port: 8000
|
||||
|
||||
ingress:
|
||||
enabled: false
|
||||
className: "nginx"
|
||||
annotations: {}
|
||||
# kubernetes.io/ingress.class: nginx
|
||||
# kubernetes.io/tls-acme: "true"
|
||||
hosts:
|
||||
- host: api.example.local
|
||||
paths:
|
||||
- path: /
|
||||
pathType: ImplementationSpecific
|
||||
tls: []
|
||||
# - secretName: chart-example-tls
|
||||
# hosts:
|
||||
# - chart-example.local
|
||||
|
||||
# masterkey: changeit
|
||||
|
||||
# The elements within proxy_config are rendered as config.yaml for the proxy
|
||||
# Examples: https://github.com/BerriAI/litellm/tree/main/litellm/proxy/example_config_yaml
|
||||
# Reference: https://docs.litellm.ai/docs/proxy/configs
|
||||
proxy_config:
|
||||
model_list:
|
||||
# At least one model must exist for the proxy to start.
|
||||
- model_name: gpt-3.5-turbo
|
||||
litellm_params:
|
||||
model: gpt-3.5-turbo
|
||||
api_key: eXaMpLeOnLy
|
||||
general_settings:
|
||||
master_key: os.environ/PROXY_MASTER_KEY
|
||||
|
||||
resources: {}
|
||||
# We usually recommend not to specify default resources and to leave this as a conscious
|
||||
# choice for the user. This also increases chances charts run on environments with little
|
||||
# resources, such as Minikube. If you do want to specify resources, uncomment the following
|
||||
# lines, adjust them as necessary, and remove the curly braces after 'resources:'.
|
||||
# limits:
|
||||
# cpu: 100m
|
||||
# memory: 128Mi
|
||||
# requests:
|
||||
# cpu: 100m
|
||||
# memory: 128Mi
|
||||
|
||||
autoscaling:
|
||||
enabled: false
|
||||
minReplicas: 1
|
||||
maxReplicas: 100
|
||||
targetCPUUtilizationPercentage: 80
|
||||
# targetMemoryUtilizationPercentage: 80
|
||||
|
||||
# Additional volumes on the output Deployment definition.
|
||||
volumes: []
|
||||
# - name: foo
|
||||
# secret:
|
||||
# secretName: mysecret
|
||||
# optional: false
|
||||
|
||||
# Additional volumeMounts on the output Deployment definition.
|
||||
volumeMounts: []
|
||||
# - name: foo
|
||||
# mountPath: "/etc/foo"
|
||||
# readOnly: true
|
||||
|
||||
nodeSelector: {}
|
||||
|
||||
tolerations: []
|
||||
|
||||
affinity: {}
|
||||
|
||||
db:
|
||||
# Use an existing postgres server/cluster
|
||||
useExisting: false
|
||||
|
||||
# How to connect to the existing postgres server/cluster
|
||||
endpoint: localhost
|
||||
database: litellm
|
||||
secret:
|
||||
name: postgres
|
||||
usernameKey: username
|
||||
passwordKey: password
|
||||
|
||||
# Use the Stackgres Helm chart to deploy an instance of a Stackgres cluster.
|
||||
# The Stackgres Operator must already be installed within the target
|
||||
# Kubernetes cluster.
|
||||
# TODO: Stackgres deployment currently unsupported
|
||||
useStackgresOperator: false
|
||||
|
||||
# Use the Postgres Helm chart to create a single node, stand alone postgres
|
||||
# instance. See the "postgresql" top level key for additional configuration.
|
||||
deployStandalone: true
|
||||
|
||||
# Settings for Bitnami postgresql chart (if db.deployStandalone is true, ignored
|
||||
# otherwise)
|
||||
postgresql:
|
||||
architecture: standalone
|
||||
auth:
|
||||
username: litellm
|
||||
database: litellm
|
||||
|
||||
# You should override these on the helm command line with
|
||||
# `--set postgresql.auth.postgres-password=<some good password>,postgresql.auth.password=<some good password>`
|
||||
password: NoTaGrEaTpAsSwOrD
|
||||
postgres-password: NoTaGrEaTpAsSwOrD
|
||||
|
||||
# A secret is created by this chart (litellm-helm) with the credentials that
|
||||
# the new Postgres instance should use.
|
||||
# existingSecret: ""
|
||||
# secretKeys:
|
||||
# userPasswordKey: password
|
||||
BIN
dist/litellm-0.1.401-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.401-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.401.tar.gz
vendored
BIN
dist/litellm-0.1.401.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.432-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.432-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.432.tar.gz
vendored
BIN
dist/litellm-0.1.432.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.434-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.434-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.434.tar.gz
vendored
BIN
dist/litellm-0.1.434.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.435-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.435-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.435.tar.gz
vendored
BIN
dist/litellm-0.1.435.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.446-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.446-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.446.tar.gz
vendored
BIN
dist/litellm-0.1.446.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.452-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.452-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.452.tar.gz
vendored
BIN
dist/litellm-0.1.452.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.455-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.455-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.455.tar.gz
vendored
BIN
dist/litellm-0.1.455.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.456-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.456-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.456.tar.gz
vendored
BIN
dist/litellm-0.1.456.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.486-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.486-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.486.tar.gz
vendored
BIN
dist/litellm-0.1.486.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.487-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.487-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.487.tar.gz
vendored
BIN
dist/litellm-0.1.487.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.517-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.517-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.517.tar.gz
vendored
BIN
dist/litellm-0.1.517.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.535-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.535-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.535.tar.gz
vendored
BIN
dist/litellm-0.1.535.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.536-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.536-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.536.tar.gz
vendored
BIN
dist/litellm-0.1.536.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.537-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.537-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.537.tar.gz
vendored
BIN
dist/litellm-0.1.537.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.546-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.546-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.546.tar.gz
vendored
BIN
dist/litellm-0.1.546.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.547-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.547-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.547.tar.gz
vendored
BIN
dist/litellm-0.1.547.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.548-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.548-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.548.tar.gz
vendored
BIN
dist/litellm-0.1.548.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.549-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.549-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.549.tar.gz
vendored
BIN
dist/litellm-0.1.549.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.550-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.550-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.550.tar.gz
vendored
BIN
dist/litellm-0.1.550.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.551-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.551-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.551.tar.gz
vendored
BIN
dist/litellm-0.1.551.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.552-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.552-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.552.tar.gz
vendored
BIN
dist/litellm-0.1.552.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.553-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.553-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.553.tar.gz
vendored
BIN
dist/litellm-0.1.553.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.554-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.554-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.554.tar.gz
vendored
BIN
dist/litellm-0.1.554.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.555-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.555-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.555.tar.gz
vendored
BIN
dist/litellm-0.1.555.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.567-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.567-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.567.tar.gz
vendored
BIN
dist/litellm-0.1.567.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.568-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.568-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.568.tar.gz
vendored
BIN
dist/litellm-0.1.568.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.569-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.569-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.569.tar.gz
vendored
BIN
dist/litellm-0.1.569.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.585-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.585-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.585.tar.gz
vendored
BIN
dist/litellm-0.1.585.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.586-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.586-py3-none-any.whl
vendored
Binary file not shown.
BIN
dist/litellm-0.1.586.tar.gz
vendored
BIN
dist/litellm-0.1.586.tar.gz
vendored
Binary file not shown.
BIN
dist/litellm-0.1.587-py3-none-any.whl
vendored
BIN
dist/litellm-0.1.587-py3-none-any.whl
vendored
Binary file not shown.
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue