mirror of
https://github.com/BerriAI/litellm.git
synced 2026-10-10 03:28:53 +00:00
Merge remote-tracking branch 'origin' into litellm_router_search_fix
This commit is contained in:
 yuneng-jiang
commit
400e560ee5
449 changed files with 45082 additions and 23292 deletions
|
|
@ -1255,7 +1255,15 @@ jobs:
|
|||
ls
|
||||
# Add --timeout to kill hanging tests after 120s (2 min)
|
||||
# Add --durations=20 to show 20 slowest tests for debugging
|
||||
python -m pytest -vv tests/llm_translation --cov=litellm --cov-report=xml -v --junitxml=test-results/junit.xml --durations=20 -n 4 --timeout=120 --timeout_method=thread
|
||||
# Subdirectories with dedicated jobs (maintain this list as new jobs are added)
|
||||
IGNORE_DIRS=(
|
||||
"tests/llm_translation/realtime"
|
||||
)
|
||||
IGNORE_ARGS=""
|
||||
for dir in "${IGNORE_DIRS[@]}"; do
|
||||
IGNORE_ARGS="$IGNORE_ARGS --ignore=$dir"
|
||||
done
|
||||
python -m pytest -vv tests/llm_translation $IGNORE_ARGS --cov=litellm --cov-report=xml -v --junitxml=test-results/junit.xml --durations=20 -n 4 --timeout=120 --timeout_method=thread
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
|
|
@ -1271,6 +1279,54 @@ jobs:
|
|||
paths:
|
||||
- llm_translation_coverage.xml
|
||||
- llm_translation_coverage
|
||||
realtime_translation_testing:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
- run:
|
||||
name: Install Dependencies
|
||||
command: |
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install -r requirements.txt
|
||||
pip install "pytest==7.3.1"
|
||||
pip install "pytest-retry==1.6.3"
|
||||
pip install "pytest-cov==5.0.0"
|
||||
pip install "pytest-asyncio==0.21.1"
|
||||
pip install "respx==0.22.0"
|
||||
pip install "pytest-xdist==3.6.1"
|
||||
pip install "pytest-timeout==2.2.0"
|
||||
pip install "websockets"
|
||||
# Run pytest and generate JUnit XML report
|
||||
- run:
|
||||
name: Run realtime tests
|
||||
command: |
|
||||
pwd
|
||||
ls
|
||||
# Add --timeout to kill hanging tests after 120s (2 min)
|
||||
# Add --durations=20 to show 20 slowest tests for debugging
|
||||
python -m pytest -vv tests/llm_translation/realtime --cov=litellm --cov-report=xml -v --junitxml=test-results/junit.xml --durations=20 -n 4 --timeout=120 --timeout_method=thread
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml realtime_translation_coverage.xml
|
||||
mv .coverage realtime_translation_coverage
|
||||
|
||||
# Store test results
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- realtime_translation_coverage.xml
|
||||
- realtime_translation_coverage
|
||||
mcp_testing:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
|
|
@ -3532,7 +3588,7 @@ jobs:
|
|||
python -m venv venv
|
||||
. venv/bin/activate
|
||||
pip install coverage
|
||||
coverage combine llm_translation_coverage llm_responses_api_coverage ocr_coverage search_coverage mcp_coverage logging_coverage audio_coverage litellm_router_coverage litellm_router_unit_coverage local_testing_part1_coverage local_testing_part2_coverage litellm_assistants_api_coverage auth_ui_unit_tests_coverage langfuse_coverage caching_coverage litellm_proxy_unit_tests_part1_coverage litellm_proxy_unit_tests_part2_coverage image_gen_coverage pass_through_unit_tests_coverage batches_coverage litellm_security_tests_coverage guardrails_coverage litellm_mapped_tests_coverage
|
||||
coverage combine llm_translation_coverage realtime_translation_coverage llm_responses_api_coverage ocr_coverage search_coverage mcp_coverage logging_coverage audio_coverage litellm_router_coverage litellm_router_unit_coverage local_testing_part1_coverage local_testing_part2_coverage litellm_assistants_api_coverage auth_ui_unit_tests_coverage langfuse_coverage caching_coverage litellm_proxy_unit_tests_part1_coverage litellm_proxy_unit_tests_part2_coverage image_gen_coverage pass_through_unit_tests_coverage batches_coverage litellm_security_tests_coverage guardrails_coverage litellm_mapped_tests_coverage
|
||||
coverage xml
|
||||
- codecov/upload:
|
||||
file: ./coverage.xml
|
||||
|
|
@ -3754,6 +3810,9 @@ jobs:
|
|||
|
||||
cd ui/litellm-dashboard
|
||||
|
||||
# Remove node_modules and package-lock to ensure clean install (fixes dependency resolution issues)
|
||||
rm -rf node_modules package-lock.json
|
||||
|
||||
# Install dependencies first
|
||||
npm install
|
||||
|
||||
|
|
@ -4193,6 +4252,12 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- realtime_translation_testing:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- mcp_testing:
|
||||
filters:
|
||||
branches:
|
||||
|
|
@ -4304,6 +4369,7 @@ workflows:
|
|||
- upload-coverage:
|
||||
requires:
|
||||
- llm_translation_testing
|
||||
- realtime_translation_testing
|
||||
- mcp_testing
|
||||
- google_generate_content_endpoint_testing
|
||||
- guardrails_testing
|
||||
|
|
@ -4381,6 +4447,7 @@ workflows:
|
|||
- e2e_openai_endpoints
|
||||
- test_bad_database_url
|
||||
- llm_translation_testing
|
||||
- realtime_translation_testing
|
||||
- mcp_testing
|
||||
- google_generate_content_endpoint_testing
|
||||
- llm_responses_api_testing
|
||||
|
|
|
|||
65
Makefile
65
Makefile
|
|
@ -1,7 +1,10 @@
|
|||
# LiteLLM Makefile
|
||||
# Simple Makefile for running tests and basic development tasks
|
||||
|
||||
.PHONY: help test test-unit test-integration test-unit-helm lint format install-dev install-proxy-dev install-test-deps install-helm-unittest check-circular-imports check-import-safety
|
||||
.PHONY: help test test-unit test-integration test-unit-helm \
|
||||
info lint lint-dev format \
|
||||
install-dev install-proxy-dev install-test-deps \
|
||||
install-helm-unittest check-circular-imports check-import-safety
|
||||
|
||||
# Default target
|
||||
help:
|
||||
|
|
@ -25,6 +28,13 @@ help:
|
|||
@echo " make test-integration - Run integration tests"
|
||||
@echo " make test-unit-helm - Run helm unit tests"
|
||||
|
||||
# Keep PIP simple for edge cases:
|
||||
PIP := $(shell command -v pip > /dev/null 2>&1 && echo "pip" || echo "python3 -m pip")
|
||||
|
||||
# Show info
|
||||
info:
|
||||
@echo "PIP: $(PIP)"
|
||||
|
||||
# Installation targets
|
||||
install-dev:
|
||||
poetry install --with dev
|
||||
|
|
@ -34,19 +44,19 @@ install-proxy-dev:
|
|||
|
||||
# CI-compatible installations (matches GitHub workflows exactly)
|
||||
install-dev-ci:
|
||||
pip install openai==2.8.0
|
||||
$(PIP) install openai==2.8.0
|
||||
poetry install --with dev
|
||||
pip install openai==2.8.0
|
||||
$(PIP) install openai==2.8.0
|
||||
|
||||
install-proxy-dev-ci:
|
||||
poetry install --with dev,proxy-dev --extras proxy
|
||||
pip install openai==2.8.0
|
||||
$(PIP) install openai==2.8.0
|
||||
|
||||
install-test-deps: install-proxy-dev
|
||||
poetry run pip install "pytest-retry==1.6.3"
|
||||
poetry run pip install pytest-xdist
|
||||
poetry run pip install openapi-core
|
||||
cd enterprise && poetry run pip install -e . && cd ..
|
||||
poetry run $(PIP) install "pytest-retry==1.6.3"
|
||||
poetry run $(PIP) install pytest-xdist
|
||||
poetry run $(PIP) install openapi-core
|
||||
cd enterprise && poetry run $(PIP) install -e . && cd ..
|
||||
|
||||
install-helm-unittest:
|
||||
helm plugin install https://github.com/helm-unittest/helm-unittest --version v0.4.4 || echo "ignore error if plugin exists"
|
||||
|
|
@ -62,8 +72,40 @@ format-check: install-dev
|
|||
lint-ruff: install-dev
|
||||
cd litellm && poetry run ruff check . && cd ..
|
||||
|
||||
# faster linter for developing ...
|
||||
# inspiration from:
|
||||
# https://github.com/astral-sh/ruff/discussions/10977
|
||||
# https://github.com/astral-sh/ruff/discussions/4049
|
||||
lint-format-changed: install-dev
|
||||
@git diff origin/main --unified=0 --no-color -- '*.py' | \
|
||||
perl -ne '\
|
||||
if (/^diff --git a\/(.*) b\//) { $$file = $$1; } \
|
||||
if (/^@@ .* \+(\d+)(?:,(\d+))? @@/) { \
|
||||
$$start = $$1; $$count = $$2 || 1; $$end = $$start + $$count - 1; \
|
||||
print "$$file:$$start:1-$$end:999\n"; \
|
||||
}' | \
|
||||
while read range; do \
|
||||
file="$${range%%:*}"; \
|
||||
lines="$${range#*:}"; \
|
||||
echo "Formatting $$file (lines $$lines)"; \
|
||||
poetry run ruff format --range "$$lines" "$$file"; \
|
||||
done
|
||||
|
||||
lint-ruff-dev: install-dev
|
||||
@tmpfile=$$(mktemp /tmp/ruff-dev.XXXXXX) && \
|
||||
cd litellm && \
|
||||
(poetry run ruff check . --output-format=pylint || true) > "$$tmpfile" && \
|
||||
poetry run diff-quality --violations=pylint "$$tmpfile" --compare-branch=origin/main && \
|
||||
cd .. ; \
|
||||
rm -f "$$tmpfile"
|
||||
|
||||
lint-ruff-FULL-dev: install-dev
|
||||
@files=$$(git diff --name-only origin/main -- '*.py'); \
|
||||
if [ -n "$$files" ]; then echo "$$files" | xargs poetry run ruff check; \
|
||||
else echo "No changed .py files to check."; fi
|
||||
|
||||
lint-mypy: install-dev
|
||||
poetry run pip install types-requests types-setuptools types-redis types-PyYAML
|
||||
poetry run $(PIP) install types-requests types-setuptools types-redis types-PyYAML
|
||||
cd litellm && poetry run mypy . --ignore-missing-imports && cd ..
|
||||
|
||||
lint-black: format-check
|
||||
|
|
@ -72,11 +114,14 @@ check-circular-imports: install-dev
|
|||
cd litellm && poetry run python ../tests/documentation_tests/test_circular_imports.py && cd ..
|
||||
|
||||
check-import-safety: install-dev
|
||||
poetry run python -c "from litellm import *" || (echo '🚨 import failed, this means you introduced unprotected imports! 🚨'; exit 1)
|
||||
@poetry run python -c "from litellm import *; print('[from litellm import *] OK! no issues!');" || (echo '🚨 import failed, this means you introduced unprotected imports! 🚨'; exit 1)
|
||||
|
||||
# Combined linting (matches test-linting.yml workflow)
|
||||
lint: format-check lint-ruff lint-mypy check-circular-imports check-import-safety
|
||||
|
||||
# Faster linting for local development (only checks changed code)
|
||||
lint-dev: lint-format-changed lint-mypy check-circular-imports check-import-safety
|
||||
|
||||
# Testing targets
|
||||
test:
|
||||
poetry run pytest tests/
|
||||
|
|
|
|||
|
|
@ -154,6 +154,7 @@ run_grype_scans() {
|
|||
"CVE-2025-15367" # No fix available yet
|
||||
"CVE-2025-12781" # No fix available yet
|
||||
"CVE-2025-11468" # No fix available yet
|
||||
"CVE-2026-1299" # Python 3.13 email module header injection - not applicable, LiteLLM doesn't use BytesGenerator for email serialization
|
||||
)
|
||||
|
||||
# Build JSON array of allowlisted CVE IDs for jq
|
||||
|
|
|
|||
114
cookbook/livekit_agent_sdk/README.md
Normal file
114
cookbook/livekit_agent_sdk/README.md
Normal file
|
|
@ -0,0 +1,114 @@
|
|||
# LiveKit Voice Agent with LiteLLM Gateway
|
||||
|
||||
Simple example showing how to use LiveKit's xAI realtime plugin with LiteLLM as a proxy. This lets you switch between xAI, OpenAI, and Azure realtime APIs without changing your code.
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Install dependencies
|
||||
|
||||
```bash
|
||||
pip install livekit-agents[xai] websockets
|
||||
```
|
||||
|
||||
### 2. Start LiteLLM proxy
|
||||
|
||||
```bash
|
||||
# With xAI
|
||||
export XAI_API_KEY="your-xai-key"
|
||||
litellm --config config.yaml --port 4000
|
||||
```
|
||||
|
||||
### 3. Run the voice agent
|
||||
|
||||
```bash
|
||||
python main.py
|
||||
```
|
||||
|
||||
Type your message and get a voice response from Grok!
|
||||
|
||||
## Configuration
|
||||
|
||||
Set these environment variables if needed:
|
||||
|
||||
```bash
|
||||
export LITELLM_PROXY_URL="http://localhost:4000"
|
||||
export LITELLM_API_KEY="sk-1234"
|
||||
export LITELLM_MODEL="grok-voice-agent"
|
||||
```
|
||||
|
||||
Or use the defaults - connects to `http://localhost:4000` by default.
|
||||
|
||||
## Example Config File
|
||||
|
||||
Create a `config.yaml` with your realtime models:
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: grok-voice-agent
|
||||
litellm_params:
|
||||
model: xai/grok-2-vision-1212
|
||||
api_key: os.environ/XAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
|
||||
- model_name: openai-voice-agent
|
||||
litellm_params:
|
||||
model: gpt-4o-realtime-preview
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
|
||||
general_settings:
|
||||
master_key: sk-1234
|
||||
```
|
||||
|
||||
Then start: `litellm --config config.yaml --port 4000`
|
||||
|
||||
## How It Works
|
||||
|
||||
LiveKit's xAI plugin connects through LiteLLM proxy by setting `base_url`:
|
||||
|
||||
```python
|
||||
from livekit.plugins import xai
|
||||
|
||||
model = xai.realtime.RealtimeModel(
|
||||
voice="ara",
|
||||
api_key="sk-1234", # LiteLLM proxy key
|
||||
base_url="http://localhost:4000", # Point to LiteLLM
|
||||
)
|
||||
```
|
||||
|
||||
## Switching Providers
|
||||
|
||||
Just change the model in your config - no code changes needed:
|
||||
|
||||
**xAI Grok:**
|
||||
```yaml
|
||||
model: xai/grok-2-vision-1212
|
||||
```
|
||||
|
||||
**OpenAI:**
|
||||
```yaml
|
||||
model: gpt-4o-realtime-preview
|
||||
```
|
||||
|
||||
**Azure OpenAI:**
|
||||
```yaml
|
||||
model: azure/gpt-4o-realtime-preview
|
||||
api_base: https://your-endpoint.openai.azure.com/
|
||||
```
|
||||
|
||||
## Why Use LiteLLM?
|
||||
|
||||
- ✅ **Switch providers** without changing agent code
|
||||
- ✅ **Cost tracking** across all voice sessions
|
||||
- ✅ **Rate limiting** and budgets
|
||||
- ✅ **Load balancing** across multiple API keys
|
||||
- ✅ **Fallbacks** to backup models
|
||||
|
||||
## Learn More
|
||||
|
||||
- [LiveKit xAI Realtime Tutorial](/docs/tutorials/livekit_xai_realtime)
|
||||
- [xAI Realtime Docs](/docs/providers/xai_realtime)
|
||||
- [LiveKit Agents Documentation](https://docs.livekit.io/agents/)
|
||||
- [LiteLLM Realtime API](/docs/realtime)
|
||||
21
cookbook/livekit_agent_sdk/config.example.yaml
Normal file
21
cookbook/livekit_agent_sdk/config.example.yaml
Normal file
|
|
@ -0,0 +1,21 @@
|
|||
model_list:
|
||||
- model_name: grok-voice-agent
|
||||
litellm_params:
|
||||
model: xai/grok-2-vision-1212
|
||||
api_key: os.environ/XAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
|
||||
- model_name: openai-voice-agent
|
||||
litellm_params:
|
||||
model: gpt-4o-realtime-preview
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
|
||||
litellm_settings:
|
||||
drop_params: True
|
||||
telemetry: False
|
||||
|
||||
general_settings:
|
||||
master_key: sk-1234 # Change this to a secure key
|
||||
112
cookbook/livekit_agent_sdk/main.py
Normal file
112
cookbook/livekit_agent_sdk/main.py
Normal file
|
|
@ -0,0 +1,112 @@
|
|||
"""
|
||||
Simple xAI Voice Agent using LiveKit SDK with LiteLLM Gateway
|
||||
|
||||
This example shows how to use LiveKit's xAI realtime plugin through LiteLLM proxy.
|
||||
LiteLLM acts as a unified interface, allowing you to switch between xAI, OpenAI,
|
||||
and Azure realtime APIs without changing your agent code.
|
||||
"""
|
||||
import asyncio
|
||||
import json
|
||||
import os
|
||||
import websockets
|
||||
|
||||
# Configuration
|
||||
PROXY_URL = os.getenv("LITELLM_PROXY_URL", "http://localhost:4000")
|
||||
API_KEY = os.getenv("LITELLM_API_KEY", "sk-1234")
|
||||
MODEL = os.getenv("LITELLM_MODEL", "grok-voice-agent")
|
||||
|
||||
|
||||
async def run_voice_agent():
|
||||
"""
|
||||
Simple voice agent that:
|
||||
1. Connects to xAI realtime API through LiteLLM proxy
|
||||
2. Sends a user message
|
||||
3. Streams back the response
|
||||
"""
|
||||
|
||||
url = f"ws://{PROXY_URL.replace('http://', '').replace('https://', '')}/v1/realtime?model={MODEL}"
|
||||
headers = {"Authorization": f"Bearer {API_KEY}"}
|
||||
|
||||
print(f"🎙️ Connecting to voice agent...")
|
||||
print(f" Model: {MODEL}")
|
||||
print(f" Proxy: {PROXY_URL}")
|
||||
print()
|
||||
|
||||
async with websockets.connect(url, additional_headers=headers) as ws:
|
||||
# Receive initial connection event
|
||||
initial = json.loads(await ws.recv())
|
||||
print(f"✅ Connected! Event: {initial['type']}\n")
|
||||
|
||||
# Get user input
|
||||
user_message = input("💬 Your message: ").strip()
|
||||
if not user_message:
|
||||
user_message = "Tell me a fun fact about AI!"
|
||||
|
||||
print(f"\n🤖 Sending to {MODEL}...\n")
|
||||
|
||||
# Send user message
|
||||
await ws.send(json.dumps({
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{"type": "input_text", "text": user_message}]
|
||||
}
|
||||
}))
|
||||
|
||||
# Request response
|
||||
await ws.send(json.dumps({
|
||||
"type": "response.create",
|
||||
"response": {"modalities": ["text", "audio"]}
|
||||
}))
|
||||
|
||||
# Stream response
|
||||
print("🎤 Response: ", end='', flush=True)
|
||||
transcript = []
|
||||
|
||||
try:
|
||||
while True:
|
||||
msg = await asyncio.wait_for(ws.recv(), timeout=15.0)
|
||||
event = json.loads(msg)
|
||||
|
||||
# Capture transcript deltas
|
||||
if event['type'] == 'response.output_audio_transcript.delta':
|
||||
delta = event.get('delta', '')
|
||||
if delta:
|
||||
print(delta, end='', flush=True)
|
||||
transcript.append(delta)
|
||||
|
||||
# Done when response completes
|
||||
elif event['type'] == 'response.done':
|
||||
break
|
||||
|
||||
except asyncio.TimeoutError:
|
||||
pass
|
||||
|
||||
print("\n")
|
||||
|
||||
if transcript:
|
||||
print(f"✅ Complete response: {''.join(transcript)}")
|
||||
|
||||
await ws.close()
|
||||
|
||||
|
||||
def main():
|
||||
"""Run the voice agent"""
|
||||
print("=" * 70)
|
||||
print("LiveKit xAI Voice Agent via LiteLLM Proxy")
|
||||
print("=" * 70)
|
||||
print()
|
||||
|
||||
try:
|
||||
asyncio.run(run_voice_agent())
|
||||
except KeyboardInterrupt:
|
||||
print("\n\n👋 Goodbye!")
|
||||
except Exception as e:
|
||||
print(f"\n❌ Error: {e}")
|
||||
print("\nMake sure LiteLLM proxy is running:")
|
||||
print(f" litellm --config config.yaml --port 4000")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
2
cookbook/livekit_agent_sdk/requirements.txt
Normal file
2
cookbook/livekit_agent_sdk/requirements.txt
Normal file
|
|
@ -0,0 +1,2 @@
|
|||
livekit-agents[xai]>=1.3.12
|
||||
websockets>=15.0.1
|
||||
284
cookbook/nova_sonic_realtime.py
Normal file
284
cookbook/nova_sonic_realtime.py
Normal file
|
|
@ -0,0 +1,284 @@
|
|||
"""
|
||||
Client script to test Nova Sonic realtime API through LiteLLM proxy.
|
||||
|
||||
This script connects to LiteLLM proxy's realtime endpoint and enables
|
||||
speech-to-speech conversation with Bedrock Nova Sonic.
|
||||
|
||||
Prerequisites:
|
||||
- LiteLLM proxy running with Bedrock configured
|
||||
- pyaudio installed: pip install pyaudio
|
||||
- websockets installed: pip install websockets
|
||||
|
||||
Usage:
|
||||
python nova_sonic_realtime.py
|
||||
"""
|
||||
|
||||
import asyncio
|
||||
import base64
|
||||
import json
|
||||
import pyaudio
|
||||
import websockets
|
||||
from typing import Optional
|
||||
|
||||
# Audio configuration (matching Nova Sonic requirements)
|
||||
INPUT_SAMPLE_RATE = 16000 # Nova Sonic expects 16kHz input
|
||||
OUTPUT_SAMPLE_RATE = 24000 # Nova Sonic outputs 24kHz
|
||||
CHANNELS = 1
|
||||
FORMAT = pyaudio.paInt16
|
||||
CHUNK_SIZE = 1024
|
||||
|
||||
# LiteLLM proxy configuration
|
||||
LITELLM_PROXY_URL = "ws://localhost:4000/v1/realtime?model=bedrock-sonic"
|
||||
LITELLM_API_KEY = "sk-12345" # Your LiteLLM API key
|
||||
|
||||
|
||||
class RealtimeClient:
|
||||
"""Client for LiteLLM realtime API with audio support."""
|
||||
|
||||
def __init__(self, url: str, api_key: str):
|
||||
self.url = url
|
||||
self.api_key = api_key
|
||||
self.ws: Optional[websockets.WebSocketClientProtocol] = None
|
||||
self.is_active = False
|
||||
self.audio_queue = asyncio.Queue()
|
||||
self.pyaudio = pyaudio.PyAudio()
|
||||
self.input_stream = None
|
||||
self.output_stream = None
|
||||
|
||||
async def connect(self):
|
||||
"""Connect to LiteLLM proxy realtime endpoint."""
|
||||
print(f"Connecting to {self.url}...")
|
||||
|
||||
headers = {}
|
||||
if self.api_key:
|
||||
headers["Authorization"] = f"Bearer {self.api_key}"
|
||||
|
||||
self.ws = await websockets.connect(
|
||||
self.url,
|
||||
additional_headers=headers,
|
||||
max_size=10 * 1024 * 1024, # 10MB max message size
|
||||
)
|
||||
self.is_active = True
|
||||
print("✓ Connected to LiteLLM proxy")
|
||||
|
||||
async def send_session_update(self):
|
||||
"""Send session configuration."""
|
||||
session_update = {
|
||||
"type": "session.update",
|
||||
"session": {
|
||||
"instructions": "You are a friendly assistant. Keep your responses short and conversational.",
|
||||
"voice": "matthew",
|
||||
"temperature": 0.8,
|
||||
"max_response_output_tokens": 1024,
|
||||
"modalities": ["text", "audio"],
|
||||
"input_audio_format": "pcm16",
|
||||
"output_audio_format": "pcm16",
|
||||
"turn_detection": {
|
||||
"type": "server_vad",
|
||||
"threshold": 0.5,
|
||||
"prefix_padding_ms": 300,
|
||||
"silence_duration_ms": 500,
|
||||
},
|
||||
},
|
||||
}
|
||||
await self.ws.send(json.dumps(session_update))
|
||||
print("✓ Session configuration sent")
|
||||
|
||||
async def receive_messages(self):
|
||||
"""Receive and process messages from the server."""
|
||||
try:
|
||||
async for message in self.ws:
|
||||
if not self.is_active:
|
||||
break
|
||||
|
||||
try:
|
||||
data = json.loads(message)
|
||||
event_type = data.get("type")
|
||||
|
||||
if event_type == "session.created":
|
||||
print(f"✓ Session created: {data.get('session', {}).get('id')}")
|
||||
|
||||
elif event_type == "response.created":
|
||||
print("🤖 Assistant is responding...")
|
||||
|
||||
elif event_type == "response.text.delta":
|
||||
# Print text transcription
|
||||
delta = data.get("delta", "")
|
||||
print(delta, end="", flush=True)
|
||||
|
||||
elif event_type == "response.audio.delta":
|
||||
# Queue audio for playback
|
||||
audio_b64 = data.get("delta", "")
|
||||
if audio_b64:
|
||||
audio_bytes = base64.b64decode(audio_b64)
|
||||
await self.audio_queue.put(audio_bytes)
|
||||
|
||||
elif event_type == "response.text.done":
|
||||
print() # New line after text
|
||||
|
||||
elif event_type == "response.done":
|
||||
print("✓ Response complete")
|
||||
|
||||
elif event_type == "error":
|
||||
print(f"❌ Error: {data.get('error', {})}")
|
||||
|
||||
else:
|
||||
# Debug: print other event types
|
||||
print(f"[{event_type}]", end=" ")
|
||||
|
||||
except json.JSONDecodeError:
|
||||
print(f"Failed to parse message: {message[:100]}")
|
||||
|
||||
except websockets.exceptions.ConnectionClosed:
|
||||
print("\n✗ Connection closed")
|
||||
except Exception as e:
|
||||
print(f"\n✗ Error receiving messages: {e}")
|
||||
finally:
|
||||
self.is_active = False
|
||||
|
||||
async def send_audio_chunk(self, audio_bytes: bytes):
|
||||
"""Send audio chunk to server."""
|
||||
if not self.is_active or not self.ws:
|
||||
return
|
||||
|
||||
audio_b64 = base64.b64encode(audio_bytes).decode("utf-8")
|
||||
message = {
|
||||
"type": "input_audio_buffer.append",
|
||||
"audio": audio_b64,
|
||||
}
|
||||
await self.ws.send(json.dumps(message))
|
||||
|
||||
async def commit_audio_buffer(self):
|
||||
"""Commit the audio buffer to trigger processing."""
|
||||
if not self.is_active or not self.ws:
|
||||
return
|
||||
|
||||
message = {"type": "input_audio_buffer.commit"}
|
||||
await self.ws.send(json.dumps(message))
|
||||
|
||||
async def capture_audio(self):
|
||||
"""Capture audio from microphone and send to server."""
|
||||
print("\n🎤 Starting audio capture...")
|
||||
print("Speak into your microphone. Press Ctrl+C to stop.\n")
|
||||
|
||||
self.input_stream = self.pyaudio.open(
|
||||
format=FORMAT,
|
||||
channels=CHANNELS,
|
||||
rate=INPUT_SAMPLE_RATE,
|
||||
input=True,
|
||||
frames_per_buffer=CHUNK_SIZE,
|
||||
)
|
||||
|
||||
try:
|
||||
while self.is_active:
|
||||
audio_data = self.input_stream.read(CHUNK_SIZE, exception_on_overflow=False)
|
||||
await self.send_audio_chunk(audio_data)
|
||||
await asyncio.sleep(0.01) # Small delay to prevent overwhelming
|
||||
except Exception as e:
|
||||
print(f"Error capturing audio: {e}")
|
||||
finally:
|
||||
if self.input_stream:
|
||||
self.input_stream.stop_stream()
|
||||
self.input_stream.close()
|
||||
|
||||
async def play_audio(self):
|
||||
"""Play audio responses from the server."""
|
||||
print("🔊 Starting audio playback...")
|
||||
|
||||
self.output_stream = self.pyaudio.open(
|
||||
format=FORMAT,
|
||||
channels=CHANNELS,
|
||||
rate=OUTPUT_SAMPLE_RATE,
|
||||
output=True,
|
||||
frames_per_buffer=CHUNK_SIZE,
|
||||
)
|
||||
|
||||
try:
|
||||
while self.is_active:
|
||||
try:
|
||||
audio_data = await asyncio.wait_for(
|
||||
self.audio_queue.get(), timeout=0.1
|
||||
)
|
||||
if audio_data:
|
||||
self.output_stream.write(audio_data)
|
||||
except asyncio.TimeoutError:
|
||||
continue
|
||||
except Exception as e:
|
||||
print(f"Error playing audio: {e}")
|
||||
finally:
|
||||
if self.output_stream:
|
||||
self.output_stream.stop_stream()
|
||||
self.output_stream.close()
|
||||
|
||||
async def close(self):
|
||||
"""Close the connection and cleanup."""
|
||||
self.is_active = False
|
||||
|
||||
if self.ws:
|
||||
await self.ws.close()
|
||||
|
||||
if self.input_stream:
|
||||
self.input_stream.stop_stream()
|
||||
self.input_stream.close()
|
||||
|
||||
if self.output_stream:
|
||||
self.output_stream.stop_stream()
|
||||
self.output_stream.close()
|
||||
|
||||
self.pyaudio.terminate()
|
||||
print("\n✓ Connection closed")
|
||||
|
||||
|
||||
async def main():
|
||||
"""Main function to run the realtime client."""
|
||||
print("=" * 80)
|
||||
print("Bedrock Nova Sonic Realtime Client")
|
||||
print("=" * 80)
|
||||
print()
|
||||
|
||||
client = RealtimeClient(LITELLM_PROXY_URL, LITELLM_API_KEY)
|
||||
|
||||
try:
|
||||
# Connect to server
|
||||
await client.connect()
|
||||
|
||||
# Send session configuration
|
||||
await client.send_session_update()
|
||||
|
||||
# Wait a moment for session to be established
|
||||
await asyncio.sleep(0.5)
|
||||
|
||||
# Start tasks
|
||||
receive_task = asyncio.create_task(client.receive_messages())
|
||||
capture_task = asyncio.create_task(client.capture_audio())
|
||||
playback_task = asyncio.create_task(client.play_audio())
|
||||
|
||||
# Wait for user to interrupt
|
||||
await asyncio.gather(
|
||||
receive_task,
|
||||
capture_task,
|
||||
playback_task,
|
||||
return_exceptions=True,
|
||||
)
|
||||
|
||||
except KeyboardInterrupt:
|
||||
print("\n\n⚠ Interrupted by user")
|
||||
except Exception as e:
|
||||
print(f"\n❌ Error: {e}")
|
||||
import traceback
|
||||
traceback.print_exc()
|
||||
finally:
|
||||
await client.close()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
print("\nMake sure:")
|
||||
print("1. LiteLLM proxy is running on port 4000")
|
||||
print("2. Bedrock is configured in proxy_server_config.yaml")
|
||||
print("3. AWS credentials are set")
|
||||
print()
|
||||
|
||||
try:
|
||||
asyncio.run(main())
|
||||
except KeyboardInterrupt:
|
||||
print("\n\nGoodbye!")
|
||||
|
|
@ -47,7 +47,6 @@ RUN mkdir -p /var/lib/litellm/ui && \
|
|||
if [ -f "/app/enterprise/enterprise_ui/enterprise_colors.json" ]; then \
|
||||
cp /app/enterprise/enterprise_ui/enterprise_colors.json ./ui_colors.json; \
|
||||
fi && \
|
||||
rm -f package-lock.json && \
|
||||
npm install --legacy-peer-deps && \
|
||||
npm run build && \
|
||||
cp -r /app/ui/litellm-dashboard/out/* /var/lib/litellm/ui/ && \
|
||||
|
|
|
|||
378
docs/my-website/blog/claude_opus_4_6/index.md
Normal file
378
docs/my-website/blog/claude_opus_4_6/index.md
Normal file
|
|
@ -0,0 +1,378 @@
|
|||
---
|
||||
slug: claude_opus_4_6
|
||||
title: "Day 0 Support: Claude Opus 4.6"
|
||||
date: 2026-02-05T10:00:00
|
||||
authors:
|
||||
- name: Sameer Kankute
|
||||
title: SWE @ LiteLLM (LLM Translation)
|
||||
url: https://www.linkedin.com/in/sameer-kankute/
|
||||
image_url: https://pbs.twimg.com/profile_images/2001352686994907136/ONgNuSk5_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
- name: Krrish Dholakia
|
||||
title: "CEO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
description: "Day 0 support for Claude Opus 4.6 on LiteLLM AI Gateway - use across Anthropic, Azure, Vertex AI, and Bedrock."
|
||||
tags: [anthropic, claude, opus 4.6]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
LiteLLM now supports Claude Opus 4.6 on Day 0. Use it across Anthropic, Azure, Vertex AI, and Bedrock through the LiteLLM AI Gateway.
|
||||
|
||||
## Docker Image
|
||||
|
||||
```bash
|
||||
docker pull ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6
|
||||
```
|
||||
|
||||
## Usage - Anthropic
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-6
|
||||
litellm_params:
|
||||
model: anthropic/claude-opus-4-6
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e ANTHROPIC_API_KEY=$ANTHROPIC_API_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Azure
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-6
|
||||
litellm_params:
|
||||
model: azure_ai/claude-opus-4-6
|
||||
api_key: os.environ/AZURE_AI_API_KEY
|
||||
api_base: os.environ/AZURE_AI_API_BASE # https://<resource>.services.ai.azure.com
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e AZURE_AI_API_KEY=$AZURE_AI_API_KEY \
|
||||
-e AZURE_AI_API_BASE=$AZURE_AI_API_BASE \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Vertex AI
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-6
|
||||
litellm_params:
|
||||
model: vertex_ai/claude-opus-4-6
|
||||
vertex_project: os.environ/VERTEX_PROJECT
|
||||
vertex_location: us-east5
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e VERTEX_PROJECT=$VERTEX_PROJECT \
|
||||
-e GOOGLE_APPLICATION_CREDENTIALS=/app/credentials.json \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
-v $(pwd)/credentials.json:/app/credentials.json \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Usage - Bedrock
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: claude-opus-4-6
|
||||
litellm_params:
|
||||
model: bedrock/anthropic.claude-opus-4-6-v1:0
|
||||
aws_access_key_id: os.environ/AWS_ACCESS_KEY_ID
|
||||
aws_secret_access_key: os.environ/AWS_SECRET_ACCESS_KEY
|
||||
aws_region_name: us-east-1
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e AWS_ACCESS_KEY_ID=$AWS_ACCESS_KEY_ID \
|
||||
-e AWS_SECRET_ACCESS_KEY=$AWS_SECRET_ACCESS_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:litellm_stable_release_branch-v1.80.0-stable.opus-4-6 \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Compaction
|
||||
|
||||
Litellm supports enabling compaction for the new claude-opus-4-6.
|
||||
|
||||
### Enabling Compaction
|
||||
|
||||
To enable compaction, add the `context_management` parameter with the `compact_20260112` edit type:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What is the weather in San Francisco?"
|
||||
}
|
||||
],
|
||||
"context_management": {
|
||||
"edits": [
|
||||
{
|
||||
"type": "compact_20260112"
|
||||
}
|
||||
]
|
||||
},
|
||||
"max_tokens": 100
|
||||
}'
|
||||
```
|
||||
All the parameters supported for context_management by anthropic are supported and can be directly added. Litellm automatically adds the `compact-2026-01-12` beta header in the request.
|
||||
|
||||
|
||||
### Response with Compaction Block
|
||||
|
||||
The response will include the compaction summary in `provider_specific_fields.compaction_blocks`:
|
||||
|
||||
```json
|
||||
{
|
||||
"id": "chatcmpl-a6c105a3-4b25-419e-9551-c800633b6cb2",
|
||||
"created": 1770357619,
|
||||
"model": "claude-opus-4-6",
|
||||
"object": "chat.completion",
|
||||
"choices": [
|
||||
{
|
||||
"finish_reason": "length",
|
||||
"index": 0,
|
||||
"message": {
|
||||
"content": "I don't have access to real-time data, so I can't provide the current weather in San Francisco. To get up-to-date weather information, I'd recommend checking:\n\n- **Weather websites** like weather.com, accuweather.com, or wunderground.com\n- **Search engines** – just Google \"San Francisco weather\"\n- **Weather apps** on your phone (e.g., Apple Weather, Google Weather)\n- **National",
|
||||
"role": "assistant",
|
||||
"provider_specific_fields": {
|
||||
"compaction_blocks": [
|
||||
{
|
||||
"type": "compaction",
|
||||
"content": "Summary of the conversation: The user requested help building a web scraper..."
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
],
|
||||
"usage": {
|
||||
"completion_tokens": 100,
|
||||
"prompt_tokens": 86,
|
||||
"total_tokens": 186
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Using Compaction Blocks in Follow-up Requests
|
||||
|
||||
To continue the conversation with compaction, include the compaction block in the assistant message's `provider_specific_fields`:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "How can I build a web scraper?"
|
||||
},
|
||||
{
|
||||
"role": "assistant",
|
||||
"content": [
|
||||
{
|
||||
"type": "text",
|
||||
"text": "Certainly! To build a basic web scraper, you'll typically use a programming language like Python along with libraries such as `requests` (for fetching web pages) and `BeautifulSoup` (for parsing HTML). Here's a basic example:\n\n```python\nimport requests\nfrom bs4 import BeautifulSoup\n\nurl = 'https://example.com'\nresponse = requests.get(url)\nsoup = BeautifulSoup(response.text, 'html.parser')\n\n# Extract and print all text\ntext = soup.get_text()\nprint(text)\n```\n\nLet me know what you're interested in scraping or if you need help with a specific website!"
|
||||
}
|
||||
],
|
||||
"provider_specific_fields": {
|
||||
"compaction_blocks": [
|
||||
{
|
||||
"type": "compaction",
|
||||
"content": "Summary of the conversation: The user asked how to build a web scraper, and the assistant gave an overview using Python with requests and BeautifulSoup."
|
||||
}
|
||||
]
|
||||
}
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"content": "How do I use it to scrape product prices?"
|
||||
}
|
||||
],
|
||||
"context_management": {
|
||||
"edits": [
|
||||
{
|
||||
"type": "compact_20260112"
|
||||
}
|
||||
]
|
||||
},
|
||||
"max_tokens": 100
|
||||
}'
|
||||
```
|
||||
|
||||
### Streaming Support
|
||||
|
||||
Compaction blocks are also supported in streaming mode. You'll receive:
|
||||
- `compaction_start` event when a compaction block begins
|
||||
- `compaction_delta` events with the compaction content
|
||||
- The accumulated `compaction_blocks` in `provider_specific_fields`
|
||||
|
||||
|
||||
## Effort Levels
|
||||
|
||||
Four effort levels available: `low`, `medium`, `high` (default), and `max`. Pass directly via the `effort` parameter:
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "claude-opus-4-6",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Explain quantum computing"
|
||||
}
|
||||
],
|
||||
"effort": "max"
|
||||
}'
|
||||
```
|
||||
|
||||
## 1M Token Context (Beta)
|
||||
|
||||
Opus 4.6 supports 1M token context. Premium pricing applies for prompts exceeding 200k tokens ($10/$37.50 per million input/output tokens). LiteLLM supports cost calculations for 1M token contexts.
|
||||
|
||||
## US-Only Inference
|
||||
|
||||
Available at 1.1× token pricing. LiteLLM supports this pricing model.
|
||||
|
||||
92
docs/my-website/blog/sub_millisecond_proxy_overhead/index.md
Normal file
92
docs/my-website/blog/sub_millisecond_proxy_overhead/index.md
Normal file
|
|
@ -0,0 +1,92 @@
|
|||
---
|
||||
slug: sub-millisecond-proxy-overhead
|
||||
title: "Achieving Sub-Millisecond Proxy Overhead"
|
||||
date: 2026-02-02T10:00:00
|
||||
authors:
|
||||
- name: Alexsander Hamir
|
||||
title: "Performance Engineer, LiteLLM"
|
||||
url: https://www.linkedin.com/in/alexsander-baptista/
|
||||
image_url: https://github.com/AlexsanderHamir.png
|
||||
- name: Krrish Dholakia
|
||||
title: "CEO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
description: "Our Q1 performance target and architectural direction for achieving sub-millisecond proxy overhead on modest hardware."
|
||||
tags: [performance, architecture]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
|
||||
|
||||
# Achieving Sub-Millisecond Proxy Overhead
|
||||
|
||||
## Introduction
|
||||
|
||||
Our Q1 performance target is to aggressively move toward sub-millisecond proxy overhead on a single instance with 4 CPUs and 8 GB of RAM, and to continue pushing that boundary over time. Our broader goal is to make LiteLLM inexpensive to deploy, lightweight, and fast. This post outlines the architectural direction behind that effort.
|
||||
|
||||
Proxy overhead refers to the latency introduced by LiteLLM itself, independent of the upstream provider.
|
||||
|
||||
To measure it, we run the same workload directly against the provider and through LiteLLM at identical QPS (for example, 1,000 QPS) and compare the latency delta. To reduce noise, the load generator, LiteLLM, and a mock LLM endpoint all run on the same machine, ensuring the difference reflects proxy overhead rather than network latency.
|
||||
|
||||
---
|
||||
|
||||
## Where We're Coming From
|
||||
|
||||
Under the same benchmark originally conducted by [TensorZero](https://www.tensorzero.com/docs/gateway/benchmarks), LiteLLM previously failed at around 1,000 QPS.
|
||||
|
||||
That is no longer the case. Today, LiteLLM can be stress-tested at 1,000 QPS with no failures and can scale up to 5,000 QPS without failures on a 4-CPU, 8-GB RAM single instance setup.
|
||||
|
||||
This establishes a more up to date baseline and provides useful context as we continue working on proxy overhead and overall performance.
|
||||
|
||||
---
|
||||
|
||||
## Design Choice
|
||||
|
||||
Achieving sub-millisecond proxy overhead with a Python-based system requires being deliberate about where work happens.
|
||||
|
||||
Python is a strong fit for flexibility and extensibility: provider abstraction, configuration-driven routing, and a rich callback ecosystem. These are areas where development velocity and correctness matter more than raw throughput.
|
||||
|
||||
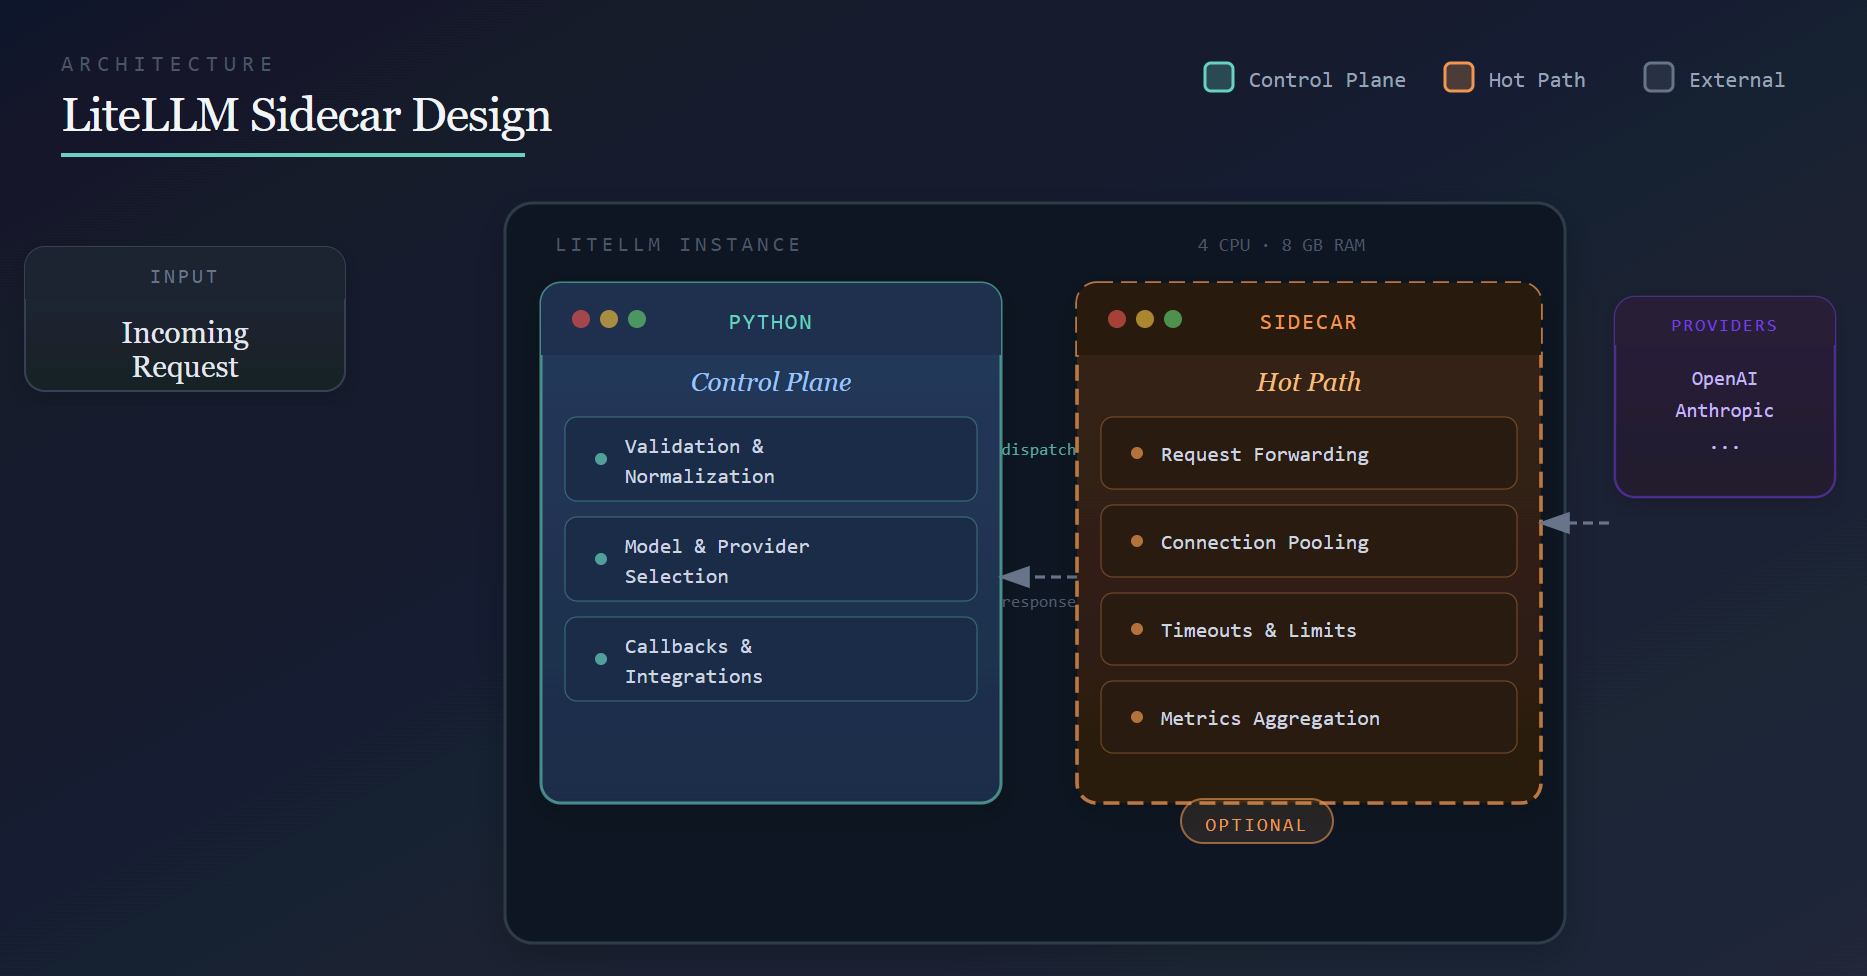
At higher request rates, however, certain classes of work become expensive when executed inside the Python process on every request. Rather than rewriting LiteLLM or introducing complex deployment requirements, we adopt an optional **sidecar architecture**.
|
||||
|
||||
This architectural change is how we intend to make LiteLLM **permanently fast**. While it supports our near-term performance targets, it is a long-term investment.
|
||||
|
||||
Python continues to own:
|
||||
|
||||
- Request validation and normalization
|
||||
- Model and provider selection
|
||||
- Callbacks and integrations
|
||||
|
||||
The sidecar owns **performance-critical execution**, such as:
|
||||
|
||||
- Efficient request forwarding
|
||||
- Connection reuse and pooling
|
||||
- Enforcing timeouts and limits
|
||||
- Aggregating high-frequency metrics
|
||||
|
||||
This separation allows each component to focus on what it does best: Python acts as the control plane, while the sidecar handles the hot path.
|
||||
|
||||
---
|
||||
|
||||
### Why the Sidecar Is Optional
|
||||
|
||||
The sidecar is intentionally **optional**.
|
||||
|
||||
This allows us to ship it incrementally, validate it under real-world workloads, and avoid making it a hard dependency before it is fully battle-tested across all LiteLLM features.
|
||||
|
||||
Just as importantly, this ensures that self-hosting LiteLLM remains simple. The sidecar is bundled and started automatically, requires no additional infrastructure, and can be disabled entirely. From a user's perspective, LiteLLM continues to behave like a single service.
|
||||
|
||||
As of today, the sidecar is an optimization, not a requirement.
|
||||
|
||||
---
|
||||
|
||||
## Conclusion
|
||||
|
||||
Sub-millisecond proxy overhead is not achieved through a single optimization, but through architectural changes.
|
||||
|
||||
By keeping Python focused on orchestration and extensibility, and offloading performance-critical execution to a sidecar, we establish a foundation for making LiteLLM **permanently fast over time**—even on modest hardware such as a 1-CPU, 2-GB RAM instance, while keeping deployment and self-hosting simple.
|
||||
|
||||
This work extends beyond Q1, and we will continue sharing benchmarks and updates as the architecture evolves.
|
||||
|
|
@ -68,116 +68,9 @@ Follow [this guide, to add your pydantic ai agent to LiteLLM Agent Gateway](./pr
|
|||
|
||||
## Invoking your Agents
|
||||
|
||||
Use the [A2A Python SDK](https://pypi.org/project/a2a-sdk) to invoke agents through LiteLLM.
|
||||
|
||||
This example shows how to:
|
||||
1. **List available agents** - Query `/v1/agents` to see which agents your key can access
|
||||
2. **Select an agent** - Pick an agent from the list
|
||||
3. **Invoke via A2A** - Use the A2A protocol to send messages to the agent
|
||||
|
||||
```python showLineNumbers title="invoke_a2a_agent.py"
|
||||
from uuid import uuid4
|
||||
import httpx
|
||||
import asyncio
|
||||
from a2a.client import A2ACardResolver, A2AClient
|
||||
from a2a.types import MessageSendParams, SendMessageRequest
|
||||
|
||||
# === CONFIGURE THESE ===
|
||||
LITELLM_BASE_URL = "http://localhost:4000" # Your LiteLLM proxy URL
|
||||
LITELLM_VIRTUAL_KEY = "sk-1234" # Your LiteLLM Virtual Key
|
||||
# =======================
|
||||
|
||||
async def main():
|
||||
headers = {"Authorization": f"Bearer {LITELLM_VIRTUAL_KEY}"}
|
||||
|
||||
async with httpx.AsyncClient(headers=headers) as client:
|
||||
# Step 1: List available agents
|
||||
response = await client.get(f"{LITELLM_BASE_URL}/v1/agents")
|
||||
agents = response.json()
|
||||
|
||||
print("Available agents:")
|
||||
for agent in agents:
|
||||
print(f" - {agent['agent_name']} (ID: {agent['agent_id']})")
|
||||
|
||||
if not agents:
|
||||
print("No agents available for this key")
|
||||
return
|
||||
|
||||
# Step 2: Select an agent and invoke it
|
||||
selected_agent = agents[0]
|
||||
agent_id = selected_agent["agent_id"]
|
||||
agent_name = selected_agent["agent_name"]
|
||||
print(f"\nInvoking: {agent_name}")
|
||||
|
||||
# Step 3: Use A2A protocol to invoke the agent
|
||||
base_url = f"{LITELLM_BASE_URL}/a2a/{agent_id}"
|
||||
resolver = A2ACardResolver(httpx_client=client, base_url=base_url)
|
||||
agent_card = await resolver.get_agent_card()
|
||||
a2a_client = A2AClient(httpx_client=client, agent_card=agent_card)
|
||||
|
||||
request = SendMessageRequest(
|
||||
id=str(uuid4()),
|
||||
params=MessageSendParams(
|
||||
message={
|
||||
"role": "user",
|
||||
"parts": [{"kind": "text", "text": "Hello, what can you do?"}],
|
||||
"messageId": uuid4().hex,
|
||||
}
|
||||
),
|
||||
)
|
||||
response = await a2a_client.send_message(request)
|
||||
print(f"Response: {response.model_dump(mode='json', exclude_none=True, indent=4)}")
|
||||
|
||||
if __name__ == "__main__":
|
||||
asyncio.run(main())
|
||||
```
|
||||
|
||||
### Streaming Responses
|
||||
|
||||
For streaming responses, use `send_message_streaming`:
|
||||
|
||||
```python showLineNumbers title="invoke_a2a_agent_streaming.py"
|
||||
from uuid import uuid4
|
||||
import httpx
|
||||
import asyncio
|
||||
from a2a.client import A2ACardResolver, A2AClient
|
||||
from a2a.types import MessageSendParams, SendStreamingMessageRequest
|
||||
|
||||
# === CONFIGURE THESE ===
|
||||
LITELLM_BASE_URL = "http://localhost:4000" # Your LiteLLM proxy URL
|
||||
LITELLM_VIRTUAL_KEY = "sk-1234" # Your LiteLLM Virtual Key
|
||||
LITELLM_AGENT_NAME = "ij-local" # Agent name registered in LiteLLM
|
||||
# =======================
|
||||
|
||||
async def main():
|
||||
base_url = f"{LITELLM_BASE_URL}/a2a/{LITELLM_AGENT_NAME}"
|
||||
headers = {"Authorization": f"Bearer {LITELLM_VIRTUAL_KEY}"}
|
||||
|
||||
async with httpx.AsyncClient(headers=headers) as httpx_client:
|
||||
# Resolve agent card and create client
|
||||
resolver = A2ACardResolver(httpx_client=httpx_client, base_url=base_url)
|
||||
agent_card = await resolver.get_agent_card()
|
||||
client = A2AClient(httpx_client=httpx_client, agent_card=agent_card)
|
||||
|
||||
# Send a streaming message
|
||||
request = SendStreamingMessageRequest(
|
||||
id=str(uuid4()),
|
||||
params=MessageSendParams(
|
||||
message={
|
||||
"role": "user",
|
||||
"parts": [{"kind": "text", "text": "Hello, what can you do?"}],
|
||||
"messageId": uuid4().hex,
|
||||
}
|
||||
),
|
||||
)
|
||||
|
||||
# Stream the response
|
||||
async for chunk in client.send_message_streaming(request):
|
||||
print(chunk.model_dump(mode="json", exclude_none=True))
|
||||
|
||||
if __name__ == "__main__":
|
||||
asyncio.run(main())
|
||||
```
|
||||
See the [Invoking A2A Agents](./a2a_invoking_agents) guide to learn how to call your agents using:
|
||||
- **A2A SDK** - Native A2A protocol with full support for tasks and artifacts
|
||||
- **OpenAI SDK** - Familiar `/chat/completions` interface with `a2a/` model prefix
|
||||
|
||||
## Tracking Agent Logs
|
||||
|
||||
|
|
|
|||
280
docs/my-website/docs/a2a_invoking_agents.md
Normal file
280
docs/my-website/docs/a2a_invoking_agents.md
Normal file
|
|
@ -0,0 +1,280 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Invoking A2A Agents
|
||||
|
||||
Learn how to invoke A2A agents through LiteLLM using different methods.
|
||||
|
||||
:::tip Deploy Your Own A2A Agent
|
||||
|
||||
Want to test with your own agent? Deploy this template A2A agent powered by Google Gemini:
|
||||
|
||||
[**shin-bot-litellm/a2a-gemini-agent**](https://github.com/shin-bot-litellm/a2a-gemini-agent) - Simple deployable A2A agent with streaming support
|
||||
|
||||
:::
|
||||
|
||||
## A2A SDK
|
||||
|
||||
Use the [A2A Python SDK](https://pypi.org/project/a2a-sdk) to invoke agents through LiteLLM using the A2A protocol.
|
||||
|
||||
### Non-Streaming
|
||||
|
||||
This example shows how to:
|
||||
1. **List available agents** - Query `/v1/agents` to see which agents your key can access
|
||||
2. **Select an agent** - Pick an agent from the list
|
||||
3. **Invoke via A2A** - Use the A2A protocol to send messages to the agent
|
||||
|
||||
```python showLineNumbers title="invoke_a2a_agent.py"
|
||||
from uuid import uuid4
|
||||
import httpx
|
||||
import asyncio
|
||||
from a2a.client import A2ACardResolver, A2AClient
|
||||
from a2a.types import MessageSendParams, SendMessageRequest
|
||||
|
||||
# === CONFIGURE THESE ===
|
||||
LITELLM_BASE_URL = "http://localhost:4000" # Your LiteLLM proxy URL
|
||||
LITELLM_VIRTUAL_KEY = "sk-1234" # Your LiteLLM Virtual Key
|
||||
# =======================
|
||||
|
||||
async def main():
|
||||
headers = {"Authorization": f"Bearer {LITELLM_VIRTUAL_KEY}"}
|
||||
|
||||
async with httpx.AsyncClient(headers=headers) as client:
|
||||
# Step 1: List available agents
|
||||
response = await client.get(f"{LITELLM_BASE_URL}/v1/agents")
|
||||
agents = response.json()
|
||||
|
||||
print("Available agents:")
|
||||
for agent in agents:
|
||||
print(f" - {agent['agent_name']} (ID: {agent['agent_id']})")
|
||||
|
||||
if not agents:
|
||||
print("No agents available for this key")
|
||||
return
|
||||
|
||||
# Step 2: Select an agent and invoke it
|
||||
selected_agent = agents[0]
|
||||
agent_id = selected_agent["agent_id"]
|
||||
agent_name = selected_agent["agent_name"]
|
||||
print(f"\nInvoking: {agent_name}")
|
||||
|
||||
# Step 3: Use A2A protocol to invoke the agent
|
||||
base_url = f"{LITELLM_BASE_URL}/a2a/{agent_id}"
|
||||
resolver = A2ACardResolver(httpx_client=client, base_url=base_url)
|
||||
agent_card = await resolver.get_agent_card()
|
||||
a2a_client = A2AClient(httpx_client=client, agent_card=agent_card)
|
||||
|
||||
request = SendMessageRequest(
|
||||
id=str(uuid4()),
|
||||
params=MessageSendParams(
|
||||
message={
|
||||
"role": "user",
|
||||
"parts": [{"kind": "text", "text": "Hello, what can you do?"}],
|
||||
"messageId": uuid4().hex,
|
||||
}
|
||||
),
|
||||
)
|
||||
response = await a2a_client.send_message(request)
|
||||
print(f"Response: {response.model_dump(mode='json', exclude_none=True, indent=4)}")
|
||||
|
||||
if __name__ == "__main__":
|
||||
asyncio.run(main())
|
||||
```
|
||||
|
||||
### Streaming
|
||||
|
||||
For streaming responses, use `send_message_streaming`:
|
||||
|
||||
```python showLineNumbers title="invoke_a2a_agent_streaming.py"
|
||||
from uuid import uuid4
|
||||
import httpx
|
||||
import asyncio
|
||||
from a2a.client import A2ACardResolver, A2AClient
|
||||
from a2a.types import MessageSendParams, SendStreamingMessageRequest
|
||||
|
||||
# === CONFIGURE THESE ===
|
||||
LITELLM_BASE_URL = "http://localhost:4000" # Your LiteLLM proxy URL
|
||||
LITELLM_VIRTUAL_KEY = "sk-1234" # Your LiteLLM Virtual Key
|
||||
LITELLM_AGENT_NAME = "ij-local" # Agent name registered in LiteLLM
|
||||
# =======================
|
||||
|
||||
async def main():
|
||||
base_url = f"{LITELLM_BASE_URL}/a2a/{LITELLM_AGENT_NAME}"
|
||||
headers = {"Authorization": f"Bearer {LITELLM_VIRTUAL_KEY}"}
|
||||
|
||||
async with httpx.AsyncClient(headers=headers) as httpx_client:
|
||||
# Resolve agent card and create client
|
||||
resolver = A2ACardResolver(httpx_client=httpx_client, base_url=base_url)
|
||||
agent_card = await resolver.get_agent_card()
|
||||
client = A2AClient(httpx_client=httpx_client, agent_card=agent_card)
|
||||
|
||||
# Send a streaming message
|
||||
request = SendStreamingMessageRequest(
|
||||
id=str(uuid4()),
|
||||
params=MessageSendParams(
|
||||
message={
|
||||
"role": "user",
|
||||
"parts": [{"kind": "text", "text": "Tell me a long story"}],
|
||||
"messageId": uuid4().hex,
|
||||
}
|
||||
),
|
||||
)
|
||||
|
||||
# Stream the response
|
||||
async for chunk in client.send_message_streaming(request):
|
||||
print(chunk.model_dump(mode="json", exclude_none=True))
|
||||
|
||||
if __name__ == "__main__":
|
||||
asyncio.run(main())
|
||||
```
|
||||
|
||||
## /chat/completions API (OpenAI SDK)
|
||||
|
||||
You can also invoke A2A agents using the familiar OpenAI SDK by using the `a2a/` model prefix.
|
||||
|
||||
### Non-Streaming
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="python" label="Python" default>
|
||||
|
||||
```python showLineNumbers title="openai_non_streaming.py"
|
||||
import openai
|
||||
|
||||
client = openai.OpenAI(
|
||||
api_key="sk-1234", # Your LiteLLM Virtual Key
|
||||
base_url="http://localhost:4000" # Your LiteLLM proxy URL
|
||||
)
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="a2a/my-agent", # Use a2a/ prefix with your agent name
|
||||
messages=[
|
||||
{"role": "user", "content": "Hello, what can you do?"}
|
||||
]
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="typescript" label="TypeScript">
|
||||
|
||||
```typescript showLineNumbers title="openai_non_streaming.ts"
|
||||
import OpenAI from 'openai';
|
||||
|
||||
const client = new OpenAI({
|
||||
apiKey: 'sk-1234', // Your LiteLLM Virtual Key
|
||||
baseURL: 'http://localhost:4000' // Your LiteLLM proxy URL
|
||||
});
|
||||
|
||||
const response = await client.chat.completions.create({
|
||||
model: 'a2a/my-agent', // Use a2a/ prefix with your agent name
|
||||
messages: [
|
||||
{ role: 'user', content: 'Hello, what can you do?' }
|
||||
]
|
||||
});
|
||||
|
||||
console.log(response.choices[0].message.content);
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="curl" label="cURL">
|
||||
|
||||
```bash showLineNumbers title="curl_non_streaming.sh"
|
||||
curl -X POST http://localhost:4000/v1/chat/completions \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "a2a/my-agent",
|
||||
"messages": [
|
||||
{"role": "user", "content": "Hello, what can you do?"}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Streaming
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="python" label="Python" default>
|
||||
|
||||
```python showLineNumbers title="openai_streaming.py"
|
||||
import openai
|
||||
|
||||
client = openai.OpenAI(
|
||||
api_key="sk-1234", # Your LiteLLM Virtual Key
|
||||
base_url="http://localhost:4000" # Your LiteLLM proxy URL
|
||||
)
|
||||
|
||||
stream = client.chat.completions.create(
|
||||
model="a2a/my-agent", # Use a2a/ prefix with your agent name
|
||||
messages=[
|
||||
{"role": "user", "content": "Tell me a long story"}
|
||||
],
|
||||
stream=True
|
||||
)
|
||||
|
||||
for chunk in stream:
|
||||
if chunk.choices[0].delta.content:
|
||||
print(chunk.choices[0].delta.content, end="", flush=True)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="typescript" label="TypeScript">
|
||||
|
||||
```typescript showLineNumbers title="openai_streaming.ts"
|
||||
import OpenAI from 'openai';
|
||||
|
||||
const client = new OpenAI({
|
||||
apiKey: 'sk-1234', // Your LiteLLM Virtual Key
|
||||
baseURL: 'http://localhost:4000' // Your LiteLLM proxy URL
|
||||
});
|
||||
|
||||
const stream = await client.chat.completions.create({
|
||||
model: 'a2a/my-agent', // Use a2a/ prefix with your agent name
|
||||
messages: [
|
||||
{ role: 'user', content: 'Tell me a long story' }
|
||||
],
|
||||
stream: true
|
||||
});
|
||||
|
||||
for await (const chunk of stream) {
|
||||
const content = chunk.choices[0]?.delta?.content;
|
||||
if (content) {
|
||||
process.stdout.write(content);
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="curl" label="cURL">
|
||||
|
||||
```bash showLineNumbers title="curl_streaming.sh"
|
||||
curl -X POST http://localhost:4000/v1/chat/completions \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "a2a/my-agent",
|
||||
"messages": [
|
||||
{"role": "user", "content": "Tell me a long story"}
|
||||
],
|
||||
"stream": true
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Key Differences
|
||||
|
||||
| Method | Use Case | Advantages |
|
||||
|--------|----------|------------|
|
||||
| **A2A SDK** | Native A2A protocol integration | • Full A2A protocol support<br/>• Access to task states and artifacts<br/>• Context management |
|
||||
| **OpenAI SDK** | Familiar OpenAI-style interface | • Drop-in replacement for OpenAI calls<br/>• Easier migration from LLM to agent workflows<br/>• Works with existing OpenAI tooling |
|
||||
|
||||
:::tip Model Prefix
|
||||
|
||||
When using the OpenAI SDK, always prefix your agent name with `a2a/` (e.g., `a2a/my-agent`) to route requests to the A2A agent instead of an LLM provider.
|
||||
|
||||
:::
|
||||
|
|
@ -101,12 +101,11 @@ model_list:
|
|||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
litellm_settings:
|
||||
guardrails:
|
||||
guardrails:
|
||||
- guardrail_name: my_guardrail
|
||||
litellm_params:
|
||||
litellm_params:
|
||||
guardrail: my_guardrail
|
||||
mode: during_call
|
||||
api_key: os.environ/MY_GUARDRAIL_API_KEY
|
||||
|
|
|
|||
|
|
@ -18,12 +18,29 @@ Each provider uses their own search backend:
|
|||
|
||||
| Provider | Search Engine | Notes |
|
||||
|----------|---------------|-------|
|
||||
| **OpenAI** (`gpt-4o-search-preview`) | OpenAI's internal search | Real-time web data |
|
||||
| **OpenAI** (`gpt-4o-search-preview`, `gpt-4o-mini-search-preview`, `gpt-5-search-api`) | OpenAI's internal search | Real-time web data |
|
||||
| **xAI** (`grok-3`) | xAI's search + X/Twitter | Real-time social media data |
|
||||
| **Google AI/Vertex** (`gemini-2.0-flash`) | **Google Search** | Uses actual Google search results |
|
||||
| **Anthropic** (`claude-3-5-sonnet`) | Anthropic's web search | Real-time web data |
|
||||
| **Perplexity** | Perplexity's search engine | AI-powered search and reasoning |
|
||||
|
||||
:::warning Important: Only Search Models Support `web_search_options`
|
||||
For OpenAI, only dedicated search models support the `web_search_options` parameter:
|
||||
- `gpt-4o-search-preview`
|
||||
- `gpt-4o-mini-search-preview`
|
||||
- `gpt-5-search-api`
|
||||
|
||||
**Regular models like `gpt-5`, `gpt-4.1`, `gpt-4o` do not support `web_search_options`**
|
||||
:::
|
||||
|
||||
:::tip The `web_search_options` parameter is optional
|
||||
Search models (like `gpt-4o-search-preview`) **automatically search the web** even without the `web_search_options` parameter.
|
||||
|
||||
Use `web_search_options` when you need to:
|
||||
- Adjust `search_context_size` (`"low"`, `"medium"`, `"high"`)
|
||||
- Specify `user_location` for localized results
|
||||
:::
|
||||
|
||||
:::info
|
||||
**Anthropic Web Search Models**: Claude models that support web search: `claude-3-5-sonnet-latest`, `claude-3-5-sonnet-20241022`, `claude-3-5-haiku-latest`, `claude-3-5-haiku-20241022`, `claude-3-7-sonnet-20250219`
|
||||
:::
|
||||
|
|
|
|||
|
|
@ -74,6 +74,18 @@ You can find [supported data regions litellm here](../docs/data_security#support
|
|||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How to set up and verify your Enterprise License
|
||||
|
||||
1. Add your license key to the environment:
|
||||
|
||||
```env
|
||||
LITELLM_LICENSE="eyJ..."
|
||||
```
|
||||
|
||||
2. Restart LiteLLM Proxy.
|
||||
|
||||
3. Open `http://<your-proxy-host>:<port>/` — the Swagger page should show **"Enterprise Edition"** in the description. If it doesn't, check that the key is correct, unexpired, and that the proxy was fully restarted.
|
||||
|
||||
### SLA's + Professional Support
|
||||
|
||||
Professional Support can assist with LLM/Provider integrations, deployment, upgrade management, and LLM Provider troubleshooting. We can’t solve your own infrastructure-related issues but we will guide you to fix them.
|
||||
|
|
|
|||
158
docs/my-website/docs/mcp_semantic_filter.md
Normal file
158
docs/my-website/docs/mcp_semantic_filter.md
Normal file
|
|
@ -0,0 +1,158 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# MCP Semantic Tool Filter
|
||||
|
||||
Automatically filter MCP tools by semantic relevance. When you have many MCP tools registered, LiteLLM semantically matches the user's query against tool descriptions and sends only the most relevant tools to the LLM.
|
||||
|
||||
## How It Works
|
||||
|
||||
Tool search shifts tool selection from a prompt-engineering problem to a retrieval problem. Instead of injecting a large static list of tools into every prompt, the semantic filter:
|
||||
|
||||
1. Builds a semantic index of all available MCP tools on startup
|
||||
2. On each request, semantically matches the user's query against tool descriptions
|
||||
3. Returns only the top-K most relevant tools to the LLM
|
||||
|
||||
This approach improves context efficiency, increases reliability by reducing tool confusion, and enables scalability to ecosystems with hundreds or thousands of MCP tools.
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant Client
|
||||
participant LiteLLM as LiteLLM Proxy
|
||||
participant SemanticFilter as Semantic Filter
|
||||
participant MCP as MCP Registry
|
||||
participant LLM as LLM Provider
|
||||
|
||||
Note over LiteLLM,MCP: Startup: Build Semantic Index
|
||||
LiteLLM->>MCP: Fetch all registered MCP tools
|
||||
MCP->>LiteLLM: Return all tools (e.g., 50 tools)
|
||||
LiteLLM->>SemanticFilter: Build semantic router with embeddings
|
||||
SemanticFilter->>LLM: Generate embeddings for tool descriptions
|
||||
LLM->>SemanticFilter: Return embeddings
|
||||
Note over SemanticFilter: Index ready for fast lookup
|
||||
|
||||
Note over Client,LLM: Request: Semantic Tool Filtering
|
||||
Client->>LiteLLM: POST /v1/responses with MCP tools
|
||||
LiteLLM->>SemanticFilter: Expand MCP references (50 tools available)
|
||||
SemanticFilter->>SemanticFilter: Extract user query from request
|
||||
SemanticFilter->>LLM: Generate query embedding
|
||||
LLM->>SemanticFilter: Return query embedding
|
||||
SemanticFilter->>SemanticFilter: Match query against tool embeddings
|
||||
SemanticFilter->>LiteLLM: Return top-K tools (e.g., 3 most relevant)
|
||||
LiteLLM->>LLM: Forward request with filtered tools (3 tools)
|
||||
LLM->>LiteLLM: Return response
|
||||
LiteLLM->>Client: Response with headers<br/>x-litellm-semantic-filter: 50->3<br/>x-litellm-semantic-filter-tools: tool1,tool2,tool3
|
||||
```
|
||||
|
||||
## Configuration
|
||||
|
||||
Enable semantic filtering in your LiteLLM config:
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
litellm_settings:
|
||||
mcp_semantic_tool_filter:
|
||||
enabled: true
|
||||
embedding_model: "text-embedding-3-small" # Model for semantic matching
|
||||
top_k: 5 # Max tools to return
|
||||
similarity_threshold: 0.3 # Min similarity score
|
||||
```
|
||||
|
||||
**Configuration Options:**
|
||||
- `enabled` - Enable/disable semantic filtering (default: `false`)
|
||||
- `embedding_model` - Model for generating embeddings (default: `"text-embedding-3-small"`)
|
||||
- `top_k` - Maximum number of tools to return (default: `10`)
|
||||
- `similarity_threshold` - Minimum similarity score for matches (default: `0.3`)
|
||||
|
||||
## Usage
|
||||
|
||||
Use MCP tools normally with the Responses API or Chat Completions. The semantic filter runs automatically:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="responses" label="Responses API">
|
||||
|
||||
```bash title="Responses API with Semantic Filtering" showLineNumbers
|
||||
curl --location 'http://localhost:4000/v1/responses' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header "Authorization: Bearer sk-1234" \
|
||||
--data '{
|
||||
"model": "gpt-4o",
|
||||
"input": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "give me TLDR of what BerriAI/litellm repo is about",
|
||||
"type": "message"
|
||||
}
|
||||
],
|
||||
"tools": [
|
||||
{
|
||||
"type": "mcp",
|
||||
"server_url": "litellm_proxy",
|
||||
"require_approval": "never"
|
||||
}
|
||||
],
|
||||
"tool_choice": "required"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="chat" label="Chat Completions">
|
||||
|
||||
```bash title="Chat Completions with Semantic Filtering" showLineNumbers
|
||||
curl --location 'http://localhost:4000/v1/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header "Authorization: Bearer sk-1234" \
|
||||
--data '{
|
||||
"model": "gpt-4o",
|
||||
"messages": [
|
||||
{"role": "user", "content": "Search Wikipedia for LiteLLM"}
|
||||
],
|
||||
"tools": [
|
||||
{
|
||||
"type": "mcp",
|
||||
"server_url": "litellm_proxy"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Response Headers
|
||||
|
||||
The semantic filter adds diagnostic headers to every response:
|
||||
|
||||
```
|
||||
x-litellm-semantic-filter: 10->3
|
||||
x-litellm-semantic-filter-tools: wikipedia-fetch,github-search,slack-post
|
||||
```
|
||||
|
||||
- **`x-litellm-semantic-filter`** - Shows before→after tool count (e.g., `10->3` means 10 tools were filtered down to 3)
|
||||
- **`x-litellm-semantic-filter-tools`** - CSV list of the filtered tool names (max 150 chars, clipped with `...` if longer)
|
||||
|
||||
These headers help you understand which tools were selected for each request and verify the filter is working correctly.
|
||||
|
||||
## Example
|
||||
|
||||
If you have 50 MCP tools registered and make a request asking about Wikipedia, the semantic filter will:
|
||||
|
||||
1. Semantically match your query `"Search Wikipedia for LiteLLM"` against all 50 tool descriptions
|
||||
2. Select the top 5 most relevant tools (e.g., `wikipedia-fetch`, `wikipedia-search`, etc.)
|
||||
3. Pass only those 5 tools to the LLM
|
||||
4. Add headers showing `x-litellm-semantic-filter: 50->5`
|
||||
|
||||
This dramatically reduces prompt size while ensuring the LLM has access to the right tools for the task.
|
||||
|
||||
## Performance
|
||||
|
||||
The semantic filter is optimized for production:
|
||||
- Router builds once on startup (no per-request overhead)
|
||||
- Semantic matching typically takes under 50ms
|
||||
- Fails gracefully - returns all tools if filtering fails
|
||||
- No impact on latency for requests without MCP tools
|
||||
|
||||
## Related
|
||||
|
||||
- [MCP Overview](./mcp.md) - Learn about MCP in LiteLLM
|
||||
- [MCP Permission Management](./mcp_control.md) - Control tool access by key/team
|
||||
- [Using MCP](./mcp_usage.md) - Complete MCP usage guide
|
||||
|
|
@ -215,6 +215,66 @@ The following parameters can be updated on a continuation of a trace by passing
|
|||
|
||||
Any other key value pairs passed into the metadata not listed in the above spec for a `litellm` completion will be added as a metadata key value pair for the generation.
|
||||
|
||||
#### Multiple Langfuse Projects (Per-Request Credentials)
|
||||
|
||||
You can send traces to different Langfuse projects per request by passing credentials directly to `completion()` or `acompletion()`. This works alongside (or instead of) the global env vars and is useful when different teams or business processes use different Langfuse projects.
|
||||
|
||||
Pass **`langfuse_public_key`**, **`langfuse_secret_key`** (or **`langfuse_secret`**), and optionally **`langfuse_host`** as keyword arguments:
|
||||
|
||||
```python
|
||||
import litellm
|
||||
from litellm import completion
|
||||
|
||||
# Optional: set a default via env for requests that don't pass credentials
|
||||
# os.environ["LANGFUSE_PUBLIC_KEY"] = "pk-default..."
|
||||
# os.environ["LANGFUSE_SECRET_KEY"] = "sk-default..."
|
||||
|
||||
litellm.success_callback = ["langfuse"]
|
||||
litellm.failure_callback = ["langfuse"]
|
||||
|
||||
# Request 1 → Langfuse Project A
|
||||
response_a = completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "Hello from team A"}],
|
||||
langfuse_public_key="pk-lf-project-a...",
|
||||
langfuse_secret_key="sk-lf-project-a...",
|
||||
langfuse_host="https://us.cloud.langfuse.com", # optional
|
||||
)
|
||||
|
||||
# Request 2 → Langfuse Project B (different project)
|
||||
response_b = completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "Hello from team B"}],
|
||||
langfuse_public_key="pk-lf-project-b...",
|
||||
langfuse_secret_key="sk-lf-project-b...",
|
||||
langfuse_host="https://eu.cloud.langfuse.com", # optional, can differ per project
|
||||
)
|
||||
```
|
||||
|
||||
Async usage with per-request credentials:
|
||||
|
||||
```python
|
||||
import litellm
|
||||
from litellm import acompletion
|
||||
|
||||
litellm.success_callback = ["langfuse"]
|
||||
litellm.failure_callback = ["langfuse"]
|
||||
|
||||
response = await acompletion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "Hi"}],
|
||||
langfuse_public_key="pk-lf-...",
|
||||
langfuse_secret_key="sk-lf-...",
|
||||
langfuse_host="https://us.cloud.langfuse.com", # optional
|
||||
)
|
||||
```
|
||||
|
||||
- **`langfuse_public_key`** – Langfuse project public key (required for per-request override).
|
||||
- **`langfuse_secret_key`** or **`langfuse_secret`** – Langfuse secret key (either name is accepted).
|
||||
- **`langfuse_host`** – Langfuse host URL (e.g. `https://us.cloud.langfuse.com`); optional, defaults to env or Langfuse cloud.
|
||||
|
||||
When these are passed, that request uses this project (and host) for the Langfuse callback; when omitted, the callback uses the global Langfuse client (from env vars if set). LiteLLM caches a Langfuse client per credential set to avoid creating a new client on every request.
|
||||
|
||||
#### Disable Logging - Specific Calls
|
||||
|
||||
To disable logging for specific calls use the `no-log` flag.
|
||||
|
|
|
|||
|
|
@ -9,7 +9,7 @@ ALL Bedrock models (Anthropic, Meta, Deepseek, Mistral, Amazon, etc.) are Suppor
|
|||
| Description | Amazon Bedrock is a fully managed service that offers a choice of high-performing foundation models (FMs). |
|
||||
| Provider Route on LiteLLM | `bedrock/`, [`bedrock/converse/`](#set-converse--invoke-route), [`bedrock/invoke/`](#set-invoke-route), [`bedrock/converse_like/`](#calling-via-internal-proxy), [`bedrock/llama/`](#deepseek-not-r1), [`bedrock/deepseek_r1/`](#deepseek-r1), [`bedrock/qwen3/`](#qwen3-imported-models), [`bedrock/qwen2/`](./bedrock_imported.md#qwen2-imported-models), [`bedrock/openai/`](./bedrock_imported.md#openai-compatible-imported-models-qwen-25-vl-etc), [`bedrock/moonshot`](./bedrock_imported.md#moonshot-kimi-k2-thinking) |
|
||||
| Provider Doc | [Amazon Bedrock ↗](https://docs.aws.amazon.com/bedrock/latest/userguide/what-is-bedrock.html) |
|
||||
| Supported OpenAI Endpoints | `/chat/completions`, `/completions`, `/embeddings`, `/images/generations` |
|
||||
| Supported OpenAI Endpoints | `/chat/completions`, `/completions`, `/embeddings`, `/images/generations`, `/v1/realtime`|
|
||||
| Rerank Endpoint | `/rerank` |
|
||||
| Pass-through Endpoint | [Supported](../pass_through/bedrock.md) |
|
||||
|
||||
|
|
|
|||
362
docs/my-website/docs/providers/bedrock_realtime_with_audio.md
Normal file
362
docs/my-website/docs/providers/bedrock_realtime_with_audio.md
Normal file
|
|
@ -0,0 +1,362 @@
|
|||
# Bedrock Realtime API
|
||||
|
||||
## Overview
|
||||
|
||||
Amazon Bedrock's Nova Sonic model supports real-time bidirectional audio streaming for voice conversations. This tutorial shows how to use it through LiteLLM Proxy.
|
||||
|
||||
## Setup
|
||||
|
||||
### 1. Configure LiteLLM Proxy
|
||||
|
||||
Create a `config.yaml` file:
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: "bedrock-sonic"
|
||||
litellm_params:
|
||||
model: bedrock/amazon.nova-sonic-v1:0
|
||||
aws_region_name: us-east-1 # or your preferred region
|
||||
model_info:
|
||||
mode: realtime
|
||||
```
|
||||
|
||||
### 2. Start LiteLLM Proxy
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
## Basic Text Interaction
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
import websockets
|
||||
import json
|
||||
|
||||
LITELLM_API_KEY = "sk-1234" # Your LiteLLM API key
|
||||
LITELLM_URL = 'ws://localhost:4000/v1/realtime?model=bedrock-sonic'
|
||||
|
||||
async def test_text_conversation():
|
||||
async with websockets.connect(
|
||||
LITELLM_URL,
|
||||
additional_headers={
|
||||
"Authorization": f"Bearer {LITELLM_API_KEY}"
|
||||
}
|
||||
) as ws:
|
||||
# Wait for session.created
|
||||
response = await ws.recv()
|
||||
print(f"Connected: {json.loads(response)['type']}")
|
||||
|
||||
# Configure session
|
||||
session_update = {
|
||||
"type": "session.update",
|
||||
"session": {
|
||||
"instructions": "You are a helpful assistant.",
|
||||
"modalities": ["text"],
|
||||
"temperature": 0.8
|
||||
}
|
||||
}
|
||||
await ws.send(json.dumps(session_update))
|
||||
|
||||
# Send a message
|
||||
message = {
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{"type": "input_text", "text": "Hello!"}]
|
||||
}
|
||||
}
|
||||
await ws.send(json.dumps(message))
|
||||
|
||||
# Trigger response
|
||||
await ws.send(json.dumps({"type": "response.create"}))
|
||||
|
||||
# Listen for response
|
||||
while True:
|
||||
response = await ws.recv()
|
||||
event = json.loads(response)
|
||||
|
||||
if event['type'] == 'response.text.delta':
|
||||
print(event['delta'], end='', flush=True)
|
||||
elif event['type'] == 'response.done':
|
||||
print("\n✓ Complete")
|
||||
break
|
||||
|
||||
if __name__ == "__main__":
|
||||
asyncio.run(test_text_conversation())
|
||||
```
|
||||
|
||||
## Audio Streaming with Voice Conversation
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
import websockets
|
||||
import json
|
||||
import base64
|
||||
import pyaudio
|
||||
|
||||
LITELLM_API_KEY = "sk-1234"
|
||||
LITELLM_URL = 'ws://localhost:4000/v1/realtime?model=bedrock-sonic'
|
||||
|
||||
# Audio configuration
|
||||
INPUT_RATE = 16000 # Nova Sonic expects 16kHz input
|
||||
OUTPUT_RATE = 24000 # Nova Sonic outputs 24kHz
|
||||
CHUNK = 1024
|
||||
|
||||
async def audio_conversation():
|
||||
# Initialize PyAudio
|
||||
p = pyaudio.PyAudio()
|
||||
|
||||
# Input stream (microphone)
|
||||
input_stream = p.open(
|
||||
format=pyaudio.paInt16,
|
||||
channels=1,
|
||||
rate=INPUT_RATE,
|
||||
input=True,
|
||||
frames_per_buffer=CHUNK
|
||||
)
|
||||
|
||||
# Output stream (speakers)
|
||||
output_stream = p.open(
|
||||
format=pyaudio.paInt16,
|
||||
channels=1,
|
||||
rate=OUTPUT_RATE,
|
||||
output=True,
|
||||
frames_per_buffer=CHUNK
|
||||
)
|
||||
|
||||
async with websockets.connect(
|
||||
LITELLM_URL,
|
||||
additional_headers={"Authorization": f"Bearer {LITELLM_API_KEY}"}
|
||||
) as ws:
|
||||
# Wait for session.created
|
||||
await ws.recv()
|
||||
print("✓ Connected")
|
||||
|
||||
# Configure session with audio
|
||||
session_update = {
|
||||
"type": "session.update",
|
||||
"session": {
|
||||
"instructions": "You are a friendly voice assistant.",
|
||||
"modalities": ["text", "audio"],
|
||||
"voice": "matthew",
|
||||
"input_audio_format": "pcm16",
|
||||
"output_audio_format": "pcm16"
|
||||
}
|
||||
}
|
||||
await ws.send(json.dumps(session_update))
|
||||
print("🎤 Speak into your microphone...")
|
||||
|
||||
async def send_audio():
|
||||
"""Capture and send audio from microphone"""
|
||||
while True:
|
||||
audio_data = input_stream.read(CHUNK, exception_on_overflow=False)
|
||||
audio_b64 = base64.b64encode(audio_data).decode('utf-8')
|
||||
await ws.send(json.dumps({
|
||||
"type": "input_audio_buffer.append",
|
||||
"audio": audio_b64
|
||||
}))
|
||||
await asyncio.sleep(0.01)
|
||||
|
||||
async def receive_audio():
|
||||
"""Receive and play audio responses"""
|
||||
while True:
|
||||
response = await ws.recv()
|
||||
event = json.loads(response)
|
||||
|
||||
if event['type'] == 'response.audio.delta':
|
||||
audio_b64 = event.get('delta', '')
|
||||
if audio_b64:
|
||||
audio_bytes = base64.b64decode(audio_b64)
|
||||
output_stream.write(audio_bytes)
|
||||
|
||||
elif event['type'] == 'response.text.delta':
|
||||
print(event['delta'], end='', flush=True)
|
||||
|
||||
elif event['type'] == 'response.done':
|
||||
print("\n✓ Response complete")
|
||||
|
||||
# Run both tasks concurrently
|
||||
await asyncio.gather(send_audio(), receive_audio())
|
||||
|
||||
if __name__ == "__main__":
|
||||
try:
|
||||
asyncio.run(audio_conversation())
|
||||
except KeyboardInterrupt:
|
||||
print("\n\nGoodbye!")
|
||||
```
|
||||
|
||||
## Using Tools/Function Calling
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
import websockets
|
||||
import json
|
||||
from datetime import datetime
|
||||
|
||||
LITELLM_API_KEY = "sk-1234"
|
||||
LITELLM_URL = 'ws://localhost:4000/v1/realtime?model=bedrock-sonic'
|
||||
|
||||
# Define tools
|
||||
TOOLS = [
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get current weather for a location",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {
|
||||
"type": "string",
|
||||
"description": "City name"
|
||||
}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
|
||||
def get_weather(location: str) -> dict:
|
||||
"""Simulated weather function"""
|
||||
return {
|
||||
"location": location,
|
||||
"temperature": 72,
|
||||
"conditions": "sunny"
|
||||
}
|
||||
|
||||
async def conversation_with_tools():
|
||||
async with websockets.connect(
|
||||
LITELLM_URL,
|
||||
additional_headers={"Authorization": f"Bearer {LITELLM_API_KEY}"}
|
||||
) as ws:
|
||||
# Wait for session.created
|
||||
await ws.recv()
|
||||
|
||||
# Configure session with tools
|
||||
session_update = {
|
||||
"type": "session.update",
|
||||
"session": {
|
||||
"instructions": "You are a helpful assistant with access to tools.",
|
||||
"modalities": ["text"],
|
||||
"tools": TOOLS
|
||||
}
|
||||
}
|
||||
await ws.send(json.dumps(session_update))
|
||||
|
||||
# Send a message that requires a tool
|
||||
message = {
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{"type": "input_text", "text": "What's the weather in San Francisco?"}]
|
||||
}
|
||||
}
|
||||
await ws.send(json.dumps(message))
|
||||
await ws.send(json.dumps({"type": "response.create"}))
|
||||
|
||||
# Handle responses and tool calls
|
||||
while True:
|
||||
response = await ws.recv()
|
||||
event = json.loads(response)
|
||||
|
||||
if event['type'] == 'response.text.delta':
|
||||
print(event['delta'], end='', flush=True)
|
||||
|
||||
elif event['type'] == 'response.function_call_arguments.done':
|
||||
# Execute the tool
|
||||
function_name = event['name']
|
||||
arguments = json.loads(event['arguments'])
|
||||
|
||||
print(f"\n🔧 Calling {function_name}({arguments})")
|
||||
result = get_weather(**arguments)
|
||||
|
||||
# Send tool result back
|
||||
tool_result = {
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "function_call_output",
|
||||
"call_id": event['call_id'],
|
||||
"output": json.dumps(result)
|
||||
}
|
||||
}
|
||||
await ws.send(json.dumps(tool_result))
|
||||
await ws.send(json.dumps({"type": "response.create"}))
|
||||
|
||||
elif event['type'] == 'response.done':
|
||||
print("\n✓ Complete")
|
||||
break
|
||||
|
||||
if __name__ == "__main__":
|
||||
asyncio.run(conversation_with_tools())
|
||||
```
|
||||
|
||||
## Configuration Options
|
||||
|
||||
### Voice Options
|
||||
Available voices: `matthew`, `joanna`, `ruth`, `stephen`, `gregory`, `amy`
|
||||
|
||||
### Audio Formats
|
||||
- **Input**: 16kHz PCM16 (mono)
|
||||
- **Output**: 24kHz PCM16 (mono)
|
||||
|
||||
### Modalities
|
||||
- `["text"]` - Text only
|
||||
- `["audio"]` - Audio only
|
||||
- `["text", "audio"]` - Both text and audio
|
||||
|
||||
## Example Test Scripts
|
||||
|
||||
Complete working examples are available in the LiteLLM repository:
|
||||
|
||||
- **Basic audio streaming**: `test_bedrock_realtime_client.py`
|
||||
- **Simple text test**: `test_bedrock_realtime_simple.py`
|
||||
- **Tool calling**: `test_bedrock_realtime_tools.py`
|
||||
|
||||
## Requirements
|
||||
|
||||
```bash
|
||||
pip install litellm websockets pyaudio
|
||||
```
|
||||
|
||||
## AWS Configuration
|
||||
|
||||
Ensure your AWS credentials are configured:
|
||||
|
||||
```bash
|
||||
export AWS_ACCESS_KEY_ID=your_access_key
|
||||
export AWS_SECRET_ACCESS_KEY=your_secret_key
|
||||
export AWS_REGION_NAME=us-east-1
|
||||
```
|
||||
|
||||
Or use AWS CLI configuration:
|
||||
|
||||
```bash
|
||||
aws configure
|
||||
```
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
### Connection Issues
|
||||
- Ensure LiteLLM proxy is running on the correct port
|
||||
- Verify AWS credentials are properly configured
|
||||
- Check that the Bedrock model is available in your region
|
||||
|
||||
### Audio Issues
|
||||
- Verify PyAudio is properly installed
|
||||
- Check microphone/speaker permissions
|
||||
- Ensure correct sample rates (16kHz input, 24kHz output)
|
||||
|
||||
### Tool Calling Issues
|
||||
- Ensure tools are properly defined in session.update
|
||||
- Verify tool results are sent back with correct call_id
|
||||
- Check that response.create is sent after tool result
|
||||
|
||||
## Related Resources
|
||||
|
||||
- [OpenAI Realtime API Documentation](https://platform.openai.com/docs/guides/realtime)
|
||||
- [Amazon Bedrock Nova Sonic Documentation](https://docs.aws.amazon.com/bedrock/latest/userguide/nova-sonic.html)
|
||||
- [LiteLLM Realtime API Documentation](/docs/realtime)
|
||||
|
|
@ -243,6 +243,13 @@ ElevenLabs provides high-quality text-to-speech capabilities through their TTS A
|
|||
| Supported Operations | `/audio/speech` |
|
||||
| Link to Provider Doc | [ElevenLabs TTS API ↗](https://elevenlabs.io/docs/api-reference/text-to-speech) |
|
||||
|
||||
### Supported Models
|
||||
|
||||
| Model | Route | Description |
|
||||
|-------|-------|-------------|
|
||||
| Eleven v3 | `elevenlabs/eleven_v3` | Most expressive model. 70+ languages, audio tags support for sound effects and pauses. |
|
||||
| Eleven Multilingual v2 | `elevenlabs/eleven_multilingual_v2` | Default TTS model. 29 languages, stable and production-ready. |
|
||||
|
||||
### Quick Start
|
||||
|
||||
#### LiteLLM Python SDK
|
||||
|
|
@ -265,6 +272,26 @@ with open("test_output.mp3", "wb") as f:
|
|||
f.write(audio.read())
|
||||
```
|
||||
|
||||
#### Using Eleven v3 with Audio Tags
|
||||
|
||||
Eleven v3 supports [audio tags](https://elevenlabs.io/docs/overview/capabilities/text-to-speech#audio-tags) for adding sound effects and pauses directly in the text:
|
||||
|
||||
```python showLineNumbers title="Eleven v3 with audio tags"
|
||||
import litellm
|
||||
import os
|
||||
|
||||
os.environ["ELEVENLABS_API_KEY"] = "your-elevenlabs-api-key"
|
||||
|
||||
audio = litellm.speech(
|
||||
model="elevenlabs/eleven_v3",
|
||||
input='Welcome back. <sfx>applause</sfx> Today we have a special guest. <pause duration="1.5s"/> Let me introduce them.',
|
||||
voice="alloy",
|
||||
)
|
||||
|
||||
with open("eleven_v3_output.mp3", "wb") as f:
|
||||
f.write(audio.read())
|
||||
```
|
||||
|
||||
#### Advanced Usage: Overriding Parameters and ElevenLabs-Specific Features
|
||||
|
||||
```python showLineNumbers title="Advanced TTS with custom parameters"
|
||||
|
|
|
|||
|
|
@ -35,11 +35,10 @@ from litellm import completion
|
|||
|
||||
response = completion(
|
||||
model="github_copilot/gpt-4",
|
||||
messages=[{"role": "user", "content": "Write a Python function to calculate fibonacci numbers"}],
|
||||
extra_headers={
|
||||
"editor-version": "vscode/1.85.1",
|
||||
"Copilot-Integration-Id": "vscode-chat"
|
||||
}
|
||||
messages=[
|
||||
{"role": "system", "content": "You are a helpful coding assistant"},
|
||||
{"role": "user", "content": "Write a Python function to calculate fibonacci numbers"}
|
||||
]
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
|
@ -50,11 +49,7 @@ from litellm import completion
|
|||
stream = completion(
|
||||
model="github_copilot/gpt-4",
|
||||
messages=[{"role": "user", "content": "Explain async/await in Python"}],
|
||||
stream=True,
|
||||
extra_headers={
|
||||
"editor-version": "vscode/1.85.1",
|
||||
"Copilot-Integration-Id": "vscode-chat"
|
||||
}
|
||||
stream=True
|
||||
)
|
||||
|
||||
for chunk in stream:
|
||||
|
|
@ -134,11 +129,7 @@ client = OpenAI(
|
|||
# Non-streaming response
|
||||
response = client.chat.completions.create(
|
||||
model="github_copilot/gpt-4",
|
||||
messages=[{"role": "user", "content": "How do I optimize this SQL query?"}],
|
||||
extra_headers={
|
||||
"editor-version": "vscode/1.85.1",
|
||||
"Copilot-Integration-Id": "vscode-chat"
|
||||
}
|
||||
messages=[{"role": "user", "content": "How do I optimize this SQL query?"}]
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
|
|
@ -156,11 +147,7 @@ response = litellm.completion(
|
|||
model="litellm_proxy/github_copilot/gpt-4",
|
||||
messages=[{"role": "user", "content": "Review this code for bugs"}],
|
||||
api_base="http://localhost:4000",
|
||||
api_key="your-proxy-api-key",
|
||||
extra_headers={
|
||||
"editor-version": "vscode/1.85.1",
|
||||
"Copilot-Integration-Id": "vscode-chat"
|
||||
}
|
||||
api_key="your-proxy-api-key"
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
|
|
@ -174,8 +161,6 @@ print(response.choices[0].message.content)
|
|||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer your-proxy-api-key" \
|
||||
-H "editor-version: vscode/1.85.1" \
|
||||
-H "Copilot-Integration-Id: vscode-chat" \
|
||||
-d '{
|
||||
"model": "github_copilot/gpt-4",
|
||||
"messages": [{"role": "user", "content": "Explain this error message"}]
|
||||
|
|
@ -211,9 +196,11 @@ export GITHUB_COPILOT_API_KEY_FILE="api-key.json"
|
|||
|
||||
### Headers
|
||||
|
||||
GitHub Copilot supports various editor-specific headers:
|
||||
LiteLLM automatically injects the required GitHub Copilot headers (simulating VSCode). You don't need to specify them manually.
|
||||
|
||||
```python showLineNumbers title="Common Headers"
|
||||
If you want to override the defaults (e.g., to simulate a different editor), you can use `extra_headers`:
|
||||
|
||||
```python showLineNumbers title="Custom Headers (Optional)"
|
||||
extra_headers = {
|
||||
"editor-version": "vscode/1.85.1", # Editor version
|
||||
"editor-plugin-version": "copilot/1.155.0", # Plugin version
|
||||
|
|
|
|||
|
|
@ -1,5 +1,8 @@
|
|||
# Sarvam.ai
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
LiteLLM supports all the text models from [Sarvam ai](https://docs.sarvam.ai/api-reference-docs/chat/chat-completions)
|
||||
|
||||
## Usage
|
||||
|
|
|
|||
|
|
@ -312,6 +312,7 @@ Gemini models with audio output capabilities using the chat completions API.
|
|||
- Only supports `pcm16` audio format
|
||||
- Streaming not yet supported
|
||||
- Must set `modalities: ["audio"]`
|
||||
- When using via LiteLLM Proxy, must include `"allowed_openai_params": ["audio", "modalities"]` in the request body to enable audio parameters
|
||||
:::
|
||||
|
||||
### Quick Start
|
||||
|
|
@ -372,7 +373,8 @@ curl http://0.0.0.0:4000/v1/chat/completions \
|
|||
"model": "gemini-tts",
|
||||
"messages": [{"role": "user", "content": "Say hello in a friendly voice"}],
|
||||
"modalities": ["audio"],
|
||||
"audio": {"voice": "Kore", "format": "pcm16"}
|
||||
"audio": {"voice": "Kore", "format": "pcm16"},
|
||||
"allowed_openai_params": ["audio", "modalities"]
|
||||
}'
|
||||
```
|
||||
|
||||
|
|
@ -389,6 +391,7 @@ response = client.chat.completions.create(
|
|||
messages=[{"role": "user", "content": "Say hello in a friendly voice"}],
|
||||
modalities=["audio"],
|
||||
audio={"voice": "Kore", "format": "pcm16"},
|
||||
extra_body={"allowed_openai_params": ["audio", "modalities"]}
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
|
|
|||
308
docs/my-website/docs/providers/xai_realtime.md
Normal file
308
docs/my-website/docs/providers/xai_realtime.md
Normal file
|
|
@ -0,0 +1,308 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# xAI Voice Agent (Realtime API)
|
||||
|
||||
xAI's Grok Voice Agent provides real-time voice conversation capabilities through WebSocket connections, enabling natural bidirectional audio interactions.
|
||||
|
||||
| Feature | Description | Comments |
|
||||
| --- | --- | --- |
|
||||
| LiteLLM AI Gateway | ✅ | |
|
||||
| LiteLLM Python SDK | ✅ | Full support via `litellm.realtime()` |
|
||||
|
||||
## Quick Start
|
||||
|
||||
### Supported Model
|
||||
|
||||
| Model | Context | Features |
|
||||
|-------|---------|----------|
|
||||
| `xai/grok-4-1-fast-non-reasoning` | 2M tokens | Voice conversation, Function calling, Vision, Audio, Web search, Caching |
|
||||
|
||||
**Note:** xAI Realtime API uses the non-reasoning variant for optimal real-time performance.
|
||||
|
||||
## Python SDK Usage
|
||||
|
||||
### Basic Realtime Connection
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
from litellm import realtime
|
||||
|
||||
async def test_xai_realtime():
|
||||
"""
|
||||
Test xAI Grok Voice Agent via LiteLLM SDK
|
||||
"""
|
||||
# Initialize realtime connection
|
||||
ws = await realtime(
|
||||
model="xai/grok-4-1-fast-non-reasoning",
|
||||
api_key="your-xai-api-key", # or set XAI_API_KEY env var
|
||||
)
|
||||
|
||||
# Connection established, xAI sends "conversation.created" event
|
||||
print("Connected to xAI Grok Voice Agent")
|
||||
|
||||
# Send a message
|
||||
await ws.send_text(json.dumps({
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{
|
||||
"type": "input_text",
|
||||
"text": "Hello! How are you?"
|
||||
}]
|
||||
}
|
||||
}))
|
||||
|
||||
# Request a response
|
||||
await ws.send_text(json.dumps({
|
||||
"type": "response.create"
|
||||
}))
|
||||
|
||||
# Listen for responses
|
||||
async for message in ws:
|
||||
data = json.loads(message)
|
||||
print(f"Received: {data['type']}")
|
||||
|
||||
if data['type'] == 'response.done':
|
||||
break
|
||||
|
||||
await ws.close()
|
||||
|
||||
# Run the async function
|
||||
asyncio.run(test_xai_realtime())
|
||||
```
|
||||
|
||||
### With Audio Input/Output
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
import json
|
||||
from litellm import realtime
|
||||
|
||||
async def xai_voice_conversation():
|
||||
"""
|
||||
Voice conversation with xAI Grok Voice Agent
|
||||
"""
|
||||
ws = await realtime(
|
||||
model="xai/grok-4-1-fast-non-reasoning",
|
||||
api_key="your-xai-api-key",
|
||||
)
|
||||
|
||||
# Send audio data (base64 encoded PCM16 24kHz)
|
||||
await ws.send_text(json.dumps({
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{
|
||||
"type": "input_audio",
|
||||
"audio": "base64_encoded_audio_data_here"
|
||||
}]
|
||||
}
|
||||
}))
|
||||
|
||||
# Request response with audio
|
||||
await ws.send_text(json.dumps({
|
||||
"type": "response.create",
|
||||
"response": {
|
||||
"modalities": ["text", "audio"],
|
||||
"instructions": "Please respond in a friendly tone."
|
||||
}
|
||||
}))
|
||||
|
||||
# Process streaming audio response
|
||||
async for message in ws:
|
||||
data = json.loads(message)
|
||||
|
||||
if data['type'] == 'response.audio.delta':
|
||||
# Handle audio chunks
|
||||
audio_chunk = data['delta']
|
||||
# Process audio_chunk (play it, save it, etc.)
|
||||
|
||||
elif data['type'] == 'response.done':
|
||||
break
|
||||
|
||||
await ws.close()
|
||||
|
||||
asyncio.run(xai_voice_conversation())
|
||||
```
|
||||
|
||||
## LiteLLM Proxy (AI Gateway) Usage
|
||||
|
||||
Load balance across multiple xAI deployments or combine with other providers.
|
||||
|
||||
### 1. Add Model to Config
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: grok-voice-agent
|
||||
litellm_params:
|
||||
model: xai/grok-4-1-fast-non-reasoning
|
||||
api_key: os.environ/XAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
|
||||
# Optional: Add fallback to OpenAI
|
||||
- model_name: grok-voice-agent
|
||||
litellm_params:
|
||||
model: openai/gpt-4o-realtime-preview-2024-10-01
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
```
|
||||
|
||||
### 2. Start Proxy
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
### 3. Test Connection
|
||||
|
||||
#### Python Client
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
import websockets
|
||||
import json
|
||||
|
||||
async def test_proxy():
|
||||
url = "ws://0.0.0.0:4000/v1/realtime?model=grok-voice-agent"
|
||||
|
||||
async with websockets.connect(
|
||||
url,
|
||||
extra_headers={
|
||||
"Authorization": "Bearer sk-1234", # Your LiteLLM proxy key
|
||||
"OpenAI-Beta": "realtime=v1"
|
||||
}
|
||||
) as ws:
|
||||
# Wait for conversation.created event from xAI
|
||||
message = await ws.recv()
|
||||
print(f"Connected: {message}")
|
||||
|
||||
# Send a message
|
||||
await ws.send(json.dumps({
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{
|
||||
"type": "input_text",
|
||||
"text": "Hello from LiteLLM proxy!"
|
||||
}]
|
||||
}
|
||||
}))
|
||||
|
||||
# Request response
|
||||
await ws.send(json.dumps({
|
||||
"type": "response.create"
|
||||
}))
|
||||
|
||||
# Listen for response
|
||||
async for message in ws:
|
||||
data = json.loads(message)
|
||||
print(f"Event: {data['type']}")
|
||||
|
||||
if data['type'] == 'response.done':
|
||||
break
|
||||
|
||||
asyncio.run(test_proxy())
|
||||
```
|
||||
|
||||
#### Node.js Client
|
||||
|
||||
```javascript
|
||||
// test.js - Run with: node test.js
|
||||
const WebSocket = require("ws");
|
||||
|
||||
const url = "ws://0.0.0.0:4000/v1/realtime?model=grok-voice-agent";
|
||||
|
||||
const ws = new WebSocket(url, {
|
||||
headers: {
|
||||
"Authorization": "Bearer sk-1234",
|
||||
"OpenAI-Beta": "realtime=v1",
|
||||
},
|
||||
});
|
||||
|
||||
ws.on("open", function open() {
|
||||
console.log("Connected to xAI via LiteLLM proxy");
|
||||
|
||||
// Send a message
|
||||
ws.send(JSON.stringify({
|
||||
type: "conversation.item.create",
|
||||
item: {
|
||||
type: "message",
|
||||
role: "user",
|
||||
content: [{
|
||||
type: "input_text",
|
||||
text: "What's the weather like?"
|
||||
}]
|
||||
}
|
||||
}));
|
||||
|
||||
// Request response
|
||||
ws.send(JSON.stringify({
|
||||
type: "response.create",
|
||||
response: {
|
||||
modalities: ["text"],
|
||||
instructions: "Please assist the user."
|
||||
}
|
||||
}));
|
||||
});
|
||||
|
||||
ws.on("message", function incoming(message) {
|
||||
const data = JSON.parse(message.toString());
|
||||
console.log(`Event: ${data.type}`);
|
||||
|
||||
if (data.type === 'response.done') {
|
||||
ws.close();
|
||||
}
|
||||
});
|
||||
|
||||
ws.on("error", function handleError(error) {
|
||||
console.error("Error: ", error);
|
||||
});
|
||||
```
|
||||
|
||||
## Key Differences from OpenAI
|
||||
|
||||
xAI's Grok Voice Agent has some differences from OpenAI's Realtime API:
|
||||
|
||||
| Feature | xAI | OpenAI | LiteLLM Handling |
|
||||
|---------|-----|--------|------------------|
|
||||
| Initial Event | `conversation.created` | `session.created` | ⚠️ Passed through as-is |
|
||||
| WebSocket URL | `wss://api.x.ai/v1/realtime` | `wss://api.openai.com/v1/realtime` | ✅ Auto-configured |
|
||||
| Model | `grok-4-1-fast-non-reasoning` | `gpt-4o-realtime-preview` | ✅ Via model prefix |
|
||||
| Audio Format | PCM16 24kHz mono | PCM16 24kHz mono | ✅ Compatible |
|
||||
| Context Window | 2M tokens | 128K tokens | N/A |
|
||||
|
||||
**What LiteLLM Handles:**
|
||||
- ✅ Automatic URL routing to correct provider
|
||||
- ✅ Authentication headers (no `OpenAI-Beta` header for xAI)
|
||||
- ✅ WebSocket connection management
|
||||
- ✅ All other event types are compatible
|
||||
|
||||
**What You Need to Handle:**
|
||||
- ⚠️ Initial event type difference (`conversation.created` vs `session.created`)
|
||||
|
||||
**Tip:** Make your client compatible with both event types:
|
||||
```python
|
||||
# Handle both providers
|
||||
if event['type'] in ['session.created', 'conversation.created']:
|
||||
print("Connection established")
|
||||
```
|
||||
|
||||
## Related Documentation
|
||||
|
||||
- [xAI Chat/Text Models](/docs/providers/xai)
|
||||
- [LiteLLM Realtime API Overview](/docs/realtime)
|
||||
- [xAI Official Documentation](https://docs.x.ai/docs)
|
||||
|
||||
## Support
|
||||
|
||||
For issues or questions:
|
||||
- [LiteLLM GitHub Issues](https://github.com/BerriAI/litellm/issues)
|
||||
- [xAI Documentation](https://docs.x.ai/docs)
|
||||
|
|
@ -23,26 +23,75 @@ From v1.76.0, SSO is now Free for up to 5 users.
|
|||
<Tabs>
|
||||
<TabItem value="okta" label="Okta SSO">
|
||||
|
||||
1. Add Okta credentials to your .env
|
||||
#### Step 1: Create an OIDC Application in Okta
|
||||
|
||||
In your Okta Admin Console, create a new **OIDC Web Application**. See [Okta's guide on creating OIDC app integrations](https://help.okta.com/en-us/content/topics/apps/apps_app_integration_wizard_oidc.htm) for detailed instructions.
|
||||
|
||||
When configuring the application:
|
||||
- **Sign-in redirect URI**: `https://<your-proxy-base-url>/sso/callback`
|
||||
- **Sign-out redirect URI** (optional): `https://<your-proxy-base-url>`
|
||||
|
||||
<Image img={require('../../img/okta_redirect_uri.png')} />
|
||||
|
||||
After creating the app, copy your **Client ID** and **Client Secret** from the application's General tab:
|
||||
|
||||
<Image img={require('../../img/okta_client_credentials.png')} />
|
||||
|
||||
#### Step 2: Assign Users to the Application
|
||||
|
||||
Ensure users are assigned to the app in the **Assignments** tab. If Federation Broker Mode is enabled, you may need to disable it to assign users manually.
|
||||
|
||||
#### Step 3: Configure Authorization Server Access Policy
|
||||
|
||||
:::warning Important
|
||||
This step is required. Without an Access Policy for your app, users will get a `no_matching_policy` error when attempting to log in.
|
||||
:::
|
||||
|
||||
1. Go to **Security** → **API**
|
||||
|
||||
<Image img={require('../../img/okta_security_api.png')} />
|
||||
|
||||
2. Select the **default** authorization server (or your custom one)
|
||||
|
||||
<Image img={require('../../img/okta_authorization_server.png')} />
|
||||
|
||||
3. Click on **Access Policies** tab, create a new policy assigned to your LiteLLM app
|
||||
4. Add a rule that allows the **Authorization Code** grant type
|
||||
|
||||
<Image img={require('../../img/okta_access_policies.png')} />
|
||||
|
||||
See [Okta's Access Policy documentation](https://help.okta.com/en-us/content/topics/security/api-access-management/access-policies.htm) for more details.
|
||||
|
||||
#### Step 4: Configure LiteLLM Environment Variables
|
||||
|
||||
```bash
|
||||
GENERIC_CLIENT_ID = "<your-okta-client-id>"
|
||||
GENERIC_CLIENT_SECRET = "<your-okta-client-secret>"
|
||||
GENERIC_AUTHORIZATION_ENDPOINT = "<your-okta-domain>/authorize" # https://dev-2kqkcd6lx6kdkuzt.us.auth0.com/authorize
|
||||
GENERIC_TOKEN_ENDPOINT = "<your-okta-domain>/token" # https://dev-2kqkcd6lx6kdkuzt.us.auth0.com/oauth/token
|
||||
GENERIC_USERINFO_ENDPOINT = "<your-okta-domain>/userinfo" # https://dev-2kqkcd6lx6kdkuzt.us.auth0.com/userinfo
|
||||
GENERIC_CLIENT_STATE = "random-string" # [OPTIONAL] REQUIRED BY OKTA, if not set random state value is generated
|
||||
GENERIC_SSO_HEADERS = "Content-Type=application/json, X-Custom-Header=custom-value" # [OPTIONAL] Comma-separated list of additional headers to add to the request - e.g. Content-Type=application/json, etc.
|
||||
GENERIC_CLIENT_ID="<your-client-id>"
|
||||
GENERIC_CLIENT_SECRET="<your-client-secret>"
|
||||
GENERIC_AUTHORIZATION_ENDPOINT="https://<your-okta-domain>/oauth2/default/v1/authorize"
|
||||
GENERIC_TOKEN_ENDPOINT="https://<your-okta-domain>/oauth2/default/v1/token"
|
||||
GENERIC_USERINFO_ENDPOINT="https://<your-okta-domain>/oauth2/default/v1/userinfo"
|
||||
GENERIC_CLIENT_STATE="random-string"
|
||||
PROXY_BASE_URL="https://<your-proxy-base-url>"
|
||||
```
|
||||
|
||||
You can get your domain specific auth/token/userinfo endpoints at `<YOUR-OKTA-DOMAIN>/.well-known/openid-configuration`
|
||||
:::tip
|
||||
You can find all OAuth endpoints at `https://<your-okta-domain>/.well-known/openid-configuration`
|
||||
:::
|
||||
|
||||
2. Add proxy url as callback_url on Okta
|
||||
#### Step 5: Test the SSO Flow
|
||||
|
||||
On Okta, add the 'callback_url' as `<proxy_base_url>/sso/callback`
|
||||
1. Start your LiteLLM proxy
|
||||
2. Navigate to `https://<your-proxy-base-url>/ui`
|
||||
3. Click the SSO login button
|
||||
4. Authenticate with Okta and verify you're redirected back to LiteLLM
|
||||
|
||||
#### Troubleshooting
|
||||
|
||||
<Image img={require('../../img/okta_callback_url.png')} />
|
||||
| Error | Cause | Solution |
|
||||
|-------|-------|----------|
|
||||
| `redirect_uri` error | Redirect URI not configured | Add `<proxy_base_url>/sso/callback` to Sign-in redirect URIs in Okta |
|
||||
| `access_denied` | User not assigned to app | Assign the user in the Assignments tab |
|
||||
| `no_matching_policy` | Missing Access Policy | Create an Access Policy in the Authorization Server (see Step 3) |
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="google" label="Google SSO">
|
||||
|
|
|
|||
|
|
@ -1,7 +1,10 @@
|
|||
# CLI Arguments
|
||||
Cli arguments, --host, --port, --num_workers
|
||||
|
||||
## --host
|
||||
This page documents all command-line interface (CLI) arguments available for the LiteLLM proxy server.
|
||||
|
||||
## Server Configuration
|
||||
|
||||
### --host
|
||||
- **Default:** `'0.0.0.0'`
|
||||
- The host for the server to listen on.
|
||||
- **Usage:**
|
||||
|
|
@ -14,7 +17,7 @@ Cli arguments, --host, --port, --num_workers
|
|||
litellm
|
||||
```
|
||||
|
||||
## --port
|
||||
### --port
|
||||
- **Default:** `4000`
|
||||
- The port to bind the server to.
|
||||
- **Usage:**
|
||||
|
|
@ -27,9 +30,9 @@ Cli arguments, --host, --port, --num_workers
|
|||
litellm
|
||||
```
|
||||
|
||||
## --num_workers
|
||||
- **Default:** `1`
|
||||
- The number of uvicorn workers to spin up.
|
||||
### --num_workers
|
||||
- **Default:** Number of logical CPUs in the system, or `4` if that cannot be determined
|
||||
- The number of uvicorn / gunicorn workers to spin up.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --num_workers 4
|
||||
|
|
@ -40,55 +43,273 @@ Cli arguments, --host, --port, --num_workers
|
|||
litellm
|
||||
```
|
||||
|
||||
## --api_base
|
||||
### --config
|
||||
- **Short form:** `-c`
|
||||
- **Default:** `None`
|
||||
- The API base for the model litellm should call.
|
||||
- Path to the proxy configuration file (e.g., config.yaml).
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --config path/to/config.yaml
|
||||
```
|
||||
|
||||
### --log_config
|
||||
- **Default:** `None`
|
||||
- **Type:** `str`
|
||||
- Path to the logging configuration file for uvicorn.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --log_config path/to/log_config.conf
|
||||
```
|
||||
|
||||
### --keepalive_timeout
|
||||
- **Default:** `None`
|
||||
- **Type:** `int`
|
||||
- Set the uvicorn keepalive timeout in seconds (uvicorn timeout_keep_alive parameter).
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --keepalive_timeout 30
|
||||
```
|
||||
- **Usage - set Environment Variable:** `KEEPALIVE_TIMEOUT`
|
||||
```shell
|
||||
export KEEPALIVE_TIMEOUT=30
|
||||
litellm
|
||||
```
|
||||
|
||||
### --max_requests_before_restart
|
||||
- **Default:** `None`
|
||||
- **Type:** `int`
|
||||
- Restart worker after this many requests. This is useful for mitigating memory growth over time.
|
||||
- For uvicorn: maps to `limit_max_requests`
|
||||
- For gunicorn: maps to `max_requests`
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --max_requests_before_restart 10000
|
||||
```
|
||||
- **Usage - set Environment Variable:** `MAX_REQUESTS_BEFORE_RESTART`
|
||||
```shell
|
||||
export MAX_REQUESTS_BEFORE_RESTART=10000
|
||||
litellm
|
||||
```
|
||||
|
||||
## Server Backend Options
|
||||
|
||||
### --run_gunicorn
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Starts proxy via gunicorn instead of uvicorn. Better for managing multiple workers in production.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --run_gunicorn
|
||||
```
|
||||
|
||||
### --run_hypercorn
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Starts proxy via hypercorn instead of uvicorn. Supports HTTP/2.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --run_hypercorn
|
||||
```
|
||||
|
||||
### --skip_server_startup
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Skip starting the server after setup (useful for database migrations only).
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --skip_server_startup
|
||||
```
|
||||
|
||||
## SSL/TLS Configuration
|
||||
|
||||
### --ssl_keyfile_path
|
||||
- **Default:** `None`
|
||||
- **Type:** `str`
|
||||
- Path to the SSL keyfile. Use this when you want to provide SSL certificate when starting proxy.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --ssl_keyfile_path /path/to/key.pem --ssl_certfile_path /path/to/cert.pem
|
||||
```
|
||||
- **Usage - set Environment Variable:** `SSL_KEYFILE_PATH`
|
||||
```shell
|
||||
export SSL_KEYFILE_PATH=/path/to/key.pem
|
||||
litellm
|
||||
```
|
||||
|
||||
### --ssl_certfile_path
|
||||
- **Default:** `None`
|
||||
- **Type:** `str`
|
||||
- Path to the SSL certfile. Use this when you want to provide SSL certificate when starting proxy.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --ssl_certfile_path /path/to/cert.pem --ssl_keyfile_path /path/to/key.pem
|
||||
```
|
||||
- **Usage - set Environment Variable:** `SSL_CERTFILE_PATH`
|
||||
```shell
|
||||
export SSL_CERTFILE_PATH=/path/to/cert.pem
|
||||
litellm
|
||||
```
|
||||
|
||||
### --ciphers
|
||||
- **Default:** `None`
|
||||
- **Type:** `str`
|
||||
- Ciphers to use for the SSL setup. Only used with `--run_hypercorn`.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --run_hypercorn --ssl_keyfile_path /path/to/key.pem --ssl_certfile_path /path/to/cert.pem --ciphers "ECDHE+AESGCM"
|
||||
```
|
||||
|
||||
## Model Configuration
|
||||
|
||||
### --model or -m
|
||||
- **Default:** `None`
|
||||
- The model name to pass to LiteLLM.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --model gpt-3.5-turbo
|
||||
```
|
||||
|
||||
### --alias
|
||||
- **Default:** `None`
|
||||
- An alias for the model, for user-friendly reference. Use this to give a litellm model name (e.g., "huggingface/codellama/CodeLlama-7b-Instruct-hf") a more user-friendly name ("codellama").
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --alias my-gpt-model
|
||||
```
|
||||
|
||||
### --api_base
|
||||
- **Default:** `None`
|
||||
- The API base for the model LiteLLM should call.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --model huggingface/tinyllama --api_base https://k58ory32yinf1ly0.us-east-1.aws.endpoints.huggingface.cloud
|
||||
```
|
||||
|
||||
## --api_version
|
||||
- **Default:** `None`
|
||||
### --api_version
|
||||
- **Default:** `2024-07-01-preview`
|
||||
- For Azure services, specify the API version.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --model azure/gpt-deployment --api_version 2023-08-01 --api_base https://<your api base>"
|
||||
```
|
||||
|
||||
## --model or -m
|
||||
### --headers
|
||||
- **Default:** `None`
|
||||
- The model name to pass to Litellm.
|
||||
- Headers for the API call (as JSON string).
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --model gpt-3.5-turbo
|
||||
litellm --model my-model --headers '{"Authorization": "Bearer token"}'
|
||||
```
|
||||
|
||||
## --test
|
||||
- **Type:** `bool` (Flag)
|
||||
- Proxy chat completions URL to make a test request.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --test
|
||||
```
|
||||
|
||||
## --health
|
||||
- **Type:** `bool` (Flag)
|
||||
- Runs a health check on all models in config.yaml
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --health
|
||||
```
|
||||
|
||||
## --alias
|
||||
### --add_key
|
||||
- **Default:** `None`
|
||||
- An alias for the model, for user-friendly reference.
|
||||
- Add a key to the model configuration.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --alias my-gpt-model
|
||||
litellm --add_key my-api-key
|
||||
```
|
||||
|
||||
## --debug
|
||||
### --save
|
||||
- **Type:** `bool` (Flag)
|
||||
- Save the model-specific config.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --model gpt-3.5-turbo --save
|
||||
```
|
||||
|
||||
## Model Parameters
|
||||
|
||||
### --temperature
|
||||
- **Default:** `None`
|
||||
- **Type:** `float`
|
||||
- Set the temperature for the model.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --temperature 0.7
|
||||
```
|
||||
|
||||
### --max_tokens
|
||||
- **Default:** `None`
|
||||
- **Type:** `int`
|
||||
- Set the maximum number of tokens for the model output.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --max_tokens 50
|
||||
```
|
||||
|
||||
### --request_timeout
|
||||
- **Default:** `None`
|
||||
- **Type:** `int`
|
||||
- Set the timeout in seconds for completion calls.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --request_timeout 300
|
||||
```
|
||||
|
||||
### --max_budget
|
||||
- **Default:** `None`
|
||||
- **Type:** `float`
|
||||
- Set max budget for API calls. Works for hosted models like OpenAI, TogetherAI, Anthropic, etc.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --max_budget 100.0
|
||||
```
|
||||
|
||||
### --drop_params
|
||||
- **Type:** `bool` (Flag)
|
||||
- Drop any unmapped params.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --drop_params
|
||||
```
|
||||
|
||||
### --add_function_to_prompt
|
||||
- **Type:** `bool` (Flag)
|
||||
- If a function passed but unsupported, pass it as a part of the prompt.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --add_function_to_prompt
|
||||
```
|
||||
|
||||
## Database Configuration
|
||||
|
||||
### --iam_token_db_auth
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Connects to an RDS database using IAM token authentication instead of a password. This is useful for AWS RDS instances that are configured to use IAM database authentication.
|
||||
- When enabled, LiteLLM will generate an IAM authentication token to connect to the database.
|
||||
- **Required Environment Variables:**
|
||||
- `DATABASE_HOST` - The RDS database host
|
||||
- `DATABASE_PORT` - The database port
|
||||
- `DATABASE_USER` - The database user
|
||||
- `DATABASE_NAME` - The database name
|
||||
- `DATABASE_SCHEMA` (optional) - The database schema
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --iam_token_db_auth
|
||||
```
|
||||
- **Usage - set Environment Variable:** `IAM_TOKEN_DB_AUTH`
|
||||
```shell
|
||||
export IAM_TOKEN_DB_AUTH=True
|
||||
export DATABASE_HOST=mydb.us-east-1.rds.amazonaws.com
|
||||
export DATABASE_PORT=5432
|
||||
export DATABASE_USER=mydbuser
|
||||
export DATABASE_NAME=mydb
|
||||
litellm
|
||||
```
|
||||
|
||||
### --use_prisma_db_push
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Use `prisma db push` instead of `prisma migrate` for database schema updates. This is useful when you want to quickly sync your database schema without creating migration files.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --use_prisma_db_push
|
||||
```
|
||||
|
||||
## Debugging
|
||||
|
||||
### --debug
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Enable debugging mode for the input.
|
||||
|
|
@ -102,10 +323,10 @@ Cli arguments, --host, --port, --num_workers
|
|||
litellm
|
||||
```
|
||||
|
||||
## --detailed_debug
|
||||
### --detailed_debug
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Enable debugging mode for the input.
|
||||
- Enable detailed debugging mode to view verbose debug logs.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --detailed_debug
|
||||
|
|
@ -116,80 +337,76 @@ Cli arguments, --host, --port, --num_workers
|
|||
litellm
|
||||
```
|
||||
|
||||
#### --temperature
|
||||
- **Default:** `None`
|
||||
- **Type:** `float`
|
||||
- Set the temperature for the model.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --temperature 0.7
|
||||
```
|
||||
|
||||
## --max_tokens
|
||||
- **Default:** `None`
|
||||
- **Type:** `int`
|
||||
- Set the maximum number of tokens for the model output.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --max_tokens 50
|
||||
```
|
||||
|
||||
## --request_timeout
|
||||
- **Default:** `6000`
|
||||
- **Type:** `int`
|
||||
- Set the timeout in seconds for completion calls.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --request_timeout 300
|
||||
```
|
||||
|
||||
## --drop_params
|
||||
### --local
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Drop any unmapped params.
|
||||
- For local debugging purposes.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --drop_params
|
||||
litellm --local
|
||||
```
|
||||
|
||||
## --add_function_to_prompt
|
||||
## Testing & Health Checks
|
||||
|
||||
### --test
|
||||
- **Type:** `bool` (Flag)
|
||||
- If a function passed but unsupported, pass it as a part of the prompt.
|
||||
- Proxy chat completions URL to make a test request to.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --add_function_to_prompt
|
||||
litellm --test
|
||||
```
|
||||
|
||||
## --config
|
||||
- Configure Litellm by providing a configuration file path.
|
||||
### --test_async
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Calls async endpoints `/queue/requests` and `/queue/response`.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --config path/to/config.yaml
|
||||
litellm --test_async
|
||||
```
|
||||
|
||||
## --telemetry
|
||||
### --num_requests
|
||||
- **Default:** `10`
|
||||
- **Type:** `int`
|
||||
- Number of requests to hit async endpoint with (used with `--test_async`).
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --test_async --num_requests 100
|
||||
```
|
||||
|
||||
### --health
|
||||
- **Type:** `bool` (Flag)
|
||||
- Runs a health check on all models in config.yaml.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --health
|
||||
```
|
||||
|
||||
## Other Options
|
||||
|
||||
### --version
|
||||
- **Short form:** `-v`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Print LiteLLM version and exit.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --version
|
||||
```
|
||||
|
||||
### --telemetry
|
||||
- **Default:** `True`
|
||||
- **Type:** `bool`
|
||||
- Help track usage of this feature.
|
||||
- Help track usage of this feature. Turn off for privacy.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --telemetry False
|
||||
```
|
||||
|
||||
|
||||
## --log_config
|
||||
- **Default:** `None`
|
||||
- **Type:** `str`
|
||||
- Specify a log configuration file for uvicorn.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --log_config path/to/log_config.conf
|
||||
```
|
||||
|
||||
## --skip_server_startup
|
||||
### --use_queue
|
||||
- **Default:** `False`
|
||||
- **Type:** `bool` (Flag)
|
||||
- Skip starting the server after setup (useful for DB migrations only).
|
||||
- To use celery workers for async endpoints.
|
||||
- **Usage:**
|
||||
```shell
|
||||
litellm --skip_server_startup
|
||||
```
|
||||
litellm --use_queue
|
||||
```
|
||||
|
|
|
|||
|
|
@ -94,7 +94,7 @@ litellm_settings:
|
|||
# /chat/completions, /completions, /embeddings, /audio/transcriptions
|
||||
mode: default_off # if default_off, you need to opt in to caching on a per call basis
|
||||
ttl: 600 # ttl for caching
|
||||
disable_copilot_system_to_assistant: False # If false (default), converts all 'system' role messages to 'assistant' for GitHub Copilot compatibility. Set to true to disable this behavior.
|
||||
disable_copilot_system_to_assistant: False # DEPRECATED - GitHub Copilot API supports system prompts.
|
||||
|
||||
callback_settings:
|
||||
otel:
|
||||
|
|
@ -197,7 +197,7 @@ router_settings:
|
|||
| disable_add_transform_inline_image_block | boolean | For Fireworks AI models - if true, turns off the auto-add of `#transform=inline` to the url of the image_url, if the model is not a vision model. |
|
||||
| disable_hf_tokenizer_download | boolean | If true, it defaults to using the openai tokenizer for all models (including huggingface models). |
|
||||
| enable_json_schema_validation | boolean | If true, enables json schema validation for all requests. |
|
||||
| disable_copilot_system_to_assistant | boolean | If false (default), converts all 'system' role messages to 'assistant' for GitHub Copilot compatibility. Set to true to disable this behavior. Useful for tools (like Claude Code) that send system messages, which Copilot does not support. |
|
||||
| disable_copilot_system_to_assistant | boolean | **DEPRECATED** - GitHub Copilot API supports system prompts. |
|
||||
|
||||
### general_settings - Reference
|
||||
|
||||
|
|
@ -321,6 +321,7 @@ router_settings:
|
|||
| redis_host | string | The host address for the Redis server. **Only set this if you have multiple instances of LiteLLM Proxy and want current tpm/rpm tracking to be shared across them** |
|
||||
| redis_password | string | The password for the Redis server. **Only set this if you have multiple instances of LiteLLM Proxy and want current tpm/rpm tracking to be shared across them** |
|
||||
| redis_port | string | The port number for the Redis server. **Only set this if you have multiple instances of LiteLLM Proxy and want current tpm/rpm tracking to be shared across them**|
|
||||
| redis_db | int | The database number for the Redis server. **Only set this if you have multiple instances of LiteLLM Proxy and want current tpm/rpm tracking to be shared across them**|
|
||||
| enable_pre_call_check | boolean | If true, checks if a call is within the model's context window before making the call. [More information here](reliability) |
|
||||
| content_policy_fallbacks | array of objects | Specifies fallback models for content policy violations. [More information here](reliability) |
|
||||
| fallbacks | array of objects | Specifies fallback models for all types of errors. [More information here](reliability) |
|
||||
|
|
@ -544,6 +545,9 @@ router_settings:
|
|||
| DEFAULT_MAX_TOKENS | Default maximum tokens for LLM calls. Default is 4096
|
||||
| DEFAULT_MAX_TOKENS_FOR_TRITON | Default maximum tokens for Triton models. Default is 2000
|
||||
| DEFAULT_MAX_REDIS_BATCH_CACHE_SIZE | Default maximum size for redis batch cache. Default is 1000
|
||||
| DEFAULT_MCP_SEMANTIC_FILTER_EMBEDDING_MODEL | Default embedding model for MCP semantic tool filtering. Default is "text-embedding-3-small"
|
||||
| DEFAULT_MCP_SEMANTIC_FILTER_SIMILARITY_THRESHOLD | Default similarity threshold for MCP semantic tool filtering. Default is 0.3
|
||||
| DEFAULT_MCP_SEMANTIC_FILTER_TOP_K | Default number of top results to return for MCP semantic tool filtering. Default is 10
|
||||
| DEFAULT_MOCK_RESPONSE_COMPLETION_TOKEN_COUNT | Default token count for mock response completions. Default is 20
|
||||
| DEFAULT_MOCK_RESPONSE_PROMPT_TOKEN_COUNT | Default token count for mock response prompts. Default is 10
|
||||
| DEFAULT_MODEL_CREATED_AT_TIME | Default creation timestamp for models. Default is 1677610602
|
||||
|
|
@ -801,6 +805,7 @@ router_settings:
|
|||
| MAXIMUM_TRACEBACK_LINES_TO_LOG | Maximum number of lines to log in traceback in LiteLLM Logs UI. Default is 100
|
||||
| MAX_RETRY_DELAY | Maximum delay in seconds for retrying requests. Default is 8.0
|
||||
| MAX_LANGFUSE_INITIALIZED_CLIENTS | Maximum number of Langfuse clients to initialize on proxy. Default is 50. This is set since langfuse initializes 1 thread everytime a client is initialized. We've had an incident in the past where we reached 100% cpu utilization because Langfuse was initialized several times.
|
||||
| MAX_MCP_SEMANTIC_FILTER_TOOLS_HEADER_LENGTH | Maximum header length for MCP semantic filter tools. Default is 150
|
||||
| MIN_NON_ZERO_TEMPERATURE | Minimum non-zero temperature value. Default is 0.0001
|
||||
| MINIMUM_PROMPT_CACHE_TOKEN_COUNT | Minimum token count for caching a prompt. Default is 1024
|
||||
| MISTRAL_API_BASE | Base URL for Mistral API. Default is https://api.mistral.ai
|
||||
|
|
|
|||
|
|
@ -9,6 +9,7 @@ LiteLLM provides flexible cost tracking and pricing customization for all LLM pr
|
|||
- **Custom Pricing** - Override default model costs or set pricing for custom models
|
||||
- **Cost Per Token** - Track costs based on input/output tokens (most common)
|
||||
- **Cost Per Second** - Track costs based on runtime (e.g., Sagemaker)
|
||||
- **Zero-Cost Models** - Bypass budget checks for free/on-premises models by setting costs to 0
|
||||
- **[Provider Discounts](./provider_discounts.md)** - Apply percentage-based discounts to specific providers
|
||||
- **[Provider Margins](./provider_margins.md)** - Add fees/margins to LLM costs for internal billing
|
||||
- **Base Model Mapping** - Ensure accurate cost tracking for Azure deployments
|
||||
|
|
@ -106,6 +107,51 @@ There are other keys you can use to specify costs for different scenarios and mo
|
|||
|
||||
These keys evolve based on how new models handle multimodality. The latest version can be found at [https://github.com/BerriAI/litellm/blob/main/model_prices_and_context_window.json](https://github.com/BerriAI/litellm/blob/main/model_prices_and_context_window.json).
|
||||
|
||||
## Zero-Cost Models (Bypass Budget Checks)
|
||||
|
||||
**Use Case**: You have on-premises or free models that should be accessible even when users exceed their budget limits.
|
||||
|
||||
**Solution** ✅: Set both `input_cost_per_token` and `output_cost_per_token` to `0` (explicitly) to bypass all budget checks for that model.
|
||||
|
||||
:::info
|
||||
|
||||
When a model is configured with zero cost, LiteLLM will automatically skip ALL budget checks (user, team, team member, end-user, organization, and global proxy budget) for requests to that model.
|
||||
|
||||
**Important**: Both costs must be **explicitly set to 0**. If costs are `null` or undefined, the model will be treated as having cost and budget checks will apply.
|
||||
|
||||
:::
|
||||
|
||||
### Configuration Example
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
# On-premises model - free to use
|
||||
- model_name: on-prem-llama
|
||||
litellm_params:
|
||||
model: ollama/llama3
|
||||
api_base: http://localhost:11434
|
||||
model_info:
|
||||
input_cost_per_token: 0 # 👈 Explicitly set to 0
|
||||
output_cost_per_token: 0 # 👈 Explicitly set to 0
|
||||
|
||||
# Paid cloud model - budget checks apply
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
# No model_info - uses default pricing from cost map
|
||||
```
|
||||
|
||||
### Behavior
|
||||
|
||||
With the above configuration:
|
||||
|
||||
- **User over budget** → Can still use `on-prem-llama` ✅, but blocked from `gpt-4` ❌
|
||||
- **Team over budget** → Can still use `on-prem-llama` ✅, but blocked from `gpt-4` ❌
|
||||
- **End-user over budget** → Can still use `on-prem-llama` ✅, but blocked from `gpt-4` ❌
|
||||
|
||||
This ensures your free/on-premises models remain accessible regardless of budget constraints, while paid models are still properly governed.
|
||||
|
||||
## Set 'base_model' for Cost Tracking (e.g. Azure deployments)
|
||||
|
||||
**Problem**: Azure returns `gpt-4` in the response when `azure/gpt-4-1106-preview` is used. This leads to inaccurate cost tracking
|
||||
|
|
|
|||
278
docs/my-website/docs/proxy/guardrails/custom_code_guardrail.md
Normal file
278
docs/my-website/docs/proxy/guardrails/custom_code_guardrail.md
Normal file
|
|
@ -0,0 +1,278 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Custom Code Guardrail
|
||||
|
||||
Write custom guardrail logic using Python-like code that runs in a sandboxed environment.
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Define the guardrail in config
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
guardrails:
|
||||
- guardrail_name: block-ssn
|
||||
litellm_params:
|
||||
guardrail: custom_code
|
||||
mode: pre_call
|
||||
custom_code: |
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
for text in inputs["texts"]:
|
||||
if regex_match(text, r"\d{3}-\d{2}-\d{4}"):
|
||||
return block("SSN detected")
|
||||
return allow()
|
||||
```
|
||||
|
||||
### 2. Start proxy
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
### 3. Test
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/chat/completions \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "gpt-4",
|
||||
"messages": [{"role": "user", "content": "My SSN is 123-45-6789"}],
|
||||
"guardrails": ["block-ssn"]
|
||||
}'
|
||||
```
|
||||
|
||||
## Configuration
|
||||
|
||||
| Parameter | Type | Required | Description |
|
||||
|-----------|------|----------|-------------|
|
||||
| `guardrail` | string | ✅ | Must be `custom_code` |
|
||||
| `mode` | string | ✅ | When to run: `pre_call`, `post_call`, `during_call` |
|
||||
| `custom_code` | string | ✅ | Python-like code with `apply_guardrail` function |
|
||||
| `default_on` | bool | ❌ | Run on all requests (default: `false`) |
|
||||
|
||||
## Writing Custom Code
|
||||
|
||||
### Function Signature
|
||||
|
||||
Your code must define an `apply_guardrail` function:
|
||||
|
||||
```python
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
# inputs: see table below
|
||||
# request_data: {"model": "...", "user_id": "...", "team_id": "...", "metadata": {...}}
|
||||
# input_type: "request" or "response"
|
||||
|
||||
return allow() # or block() or modify()
|
||||
```
|
||||
|
||||
### `inputs` Parameter
|
||||
|
||||
| Field | Type | Description |
|
||||
|-------|------|-------------|
|
||||
| `texts` | `List[str]` | Extracted text from the request/response |
|
||||
| `images` | `List[str]` | Extracted images (for image guardrails) |
|
||||
| `tools` | `List[dict]` | Tools sent to the LLM |
|
||||
| `tool_calls` | `List[dict]` | Tool calls returned from the LLM |
|
||||
| `structured_messages` | `List[dict]` | Full messages with role info (system/user/assistant) |
|
||||
| `model` | `str` | The model being used |
|
||||
|
||||
### `request_data` Parameter
|
||||
|
||||
| Field | Type | Description |
|
||||
|-------|------|-------------|
|
||||
| `model` | `str` | Model name |
|
||||
| `user_id` | `str` | User ID from API key |
|
||||
| `team_id` | `str` | Team ID from API key |
|
||||
| `end_user_id` | `str` | End user ID |
|
||||
| `metadata` | `dict` | Request metadata |
|
||||
|
||||
### Return Values
|
||||
|
||||
| Function | Description |
|
||||
|----------|-------------|
|
||||
| `allow()` | Let request/response through |
|
||||
| `block(reason)` | Reject with message |
|
||||
| `modify(texts=[], images=[], tool_calls=[])` | Transform content |
|
||||
|
||||
## Built-in Primitives
|
||||
|
||||
### Regex
|
||||
|
||||
| Function | Description |
|
||||
|----------|-------------|
|
||||
| `regex_match(text, pattern)` | Returns `True` if pattern found |
|
||||
| `regex_replace(text, pattern, replacement)` | Replace all matches |
|
||||
| `regex_find_all(text, pattern)` | Return list of matches |
|
||||
|
||||
### JSON
|
||||
|
||||
| Function | Description |
|
||||
|----------|-------------|
|
||||
| `json_parse(text)` | Parse JSON string, returns `None` on error |
|
||||
| `json_stringify(obj)` | Convert to JSON string |
|
||||
| `json_schema_valid(obj, schema)` | Validate against JSON schema |
|
||||
|
||||
### URL
|
||||
|
||||
| Function | Description |
|
||||
|----------|-------------|
|
||||
| `extract_urls(text)` | Extract all URLs from text |
|
||||
| `is_valid_url(url)` | Check if URL is valid |
|
||||
| `all_urls_valid(text)` | Check all URLs in text are valid |
|
||||
|
||||
### Code Detection
|
||||
|
||||
| Function | Description |
|
||||
|----------|-------------|
|
||||
| `detect_code(text)` | Returns `True` if code detected |
|
||||
| `detect_code_languages(text)` | Returns list of detected languages |
|
||||
| `contains_code_language(text, ["sql", "python"])` | Check for specific languages |
|
||||
|
||||
### Text Utilities
|
||||
|
||||
| Function | Description |
|
||||
|----------|-------------|
|
||||
| `contains(text, substring)` | Check if substring exists |
|
||||
| `contains_any(text, [substr1, substr2])` | Check if any substring exists |
|
||||
| `word_count(text)` | Count words |
|
||||
| `char_count(text)` | Count characters |
|
||||
| `lower(text)` / `upper(text)` / `trim(text)` | String transforms |
|
||||
|
||||
## Examples
|
||||
|
||||
### Block PII (SSN)
|
||||
|
||||
```python
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
for text in inputs["texts"]:
|
||||
if regex_match(text, r"\d{3}-\d{2}-\d{4}"):
|
||||
return block("SSN detected")
|
||||
return allow()
|
||||
```
|
||||
|
||||
### Redact Email Addresses
|
||||
|
||||
```python
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
pattern = r"[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}"
|
||||
modified = []
|
||||
for text in inputs["texts"]:
|
||||
modified.append(regex_replace(text, pattern, "[EMAIL REDACTED]"))
|
||||
return modify(texts=modified)
|
||||
```
|
||||
|
||||
### Block SQL Injection
|
||||
|
||||
```python
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
if input_type != "request":
|
||||
return allow()
|
||||
for text in inputs["texts"]:
|
||||
if contains_code_language(text, ["sql"]):
|
||||
return block("SQL code not allowed")
|
||||
return allow()
|
||||
```
|
||||
|
||||
### Validate JSON Response
|
||||
|
||||
```python
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
if input_type != "response":
|
||||
return allow()
|
||||
|
||||
schema = {
|
||||
"type": "object",
|
||||
"required": ["name", "value"]
|
||||
}
|
||||
|
||||
for text in inputs["texts"]:
|
||||
obj = json_parse(text)
|
||||
if obj is None:
|
||||
return block("Invalid JSON response")
|
||||
if not json_schema_valid(obj, schema):
|
||||
return block("Response missing required fields")
|
||||
return allow()
|
||||
```
|
||||
|
||||
### Check URLs in Response
|
||||
|
||||
```python
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
if input_type != "response":
|
||||
return allow()
|
||||
for text in inputs["texts"]:
|
||||
if not all_urls_valid(text):
|
||||
return block("Response contains invalid URLs")
|
||||
return allow()
|
||||
```
|
||||
|
||||
### Combine Multiple Checks
|
||||
|
||||
```python
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
modified = []
|
||||
|
||||
for text in inputs["texts"]:
|
||||
# Redact SSN
|
||||
text = regex_replace(text, r"\d{3}-\d{2}-\d{4}", "[SSN]")
|
||||
# Redact credit cards
|
||||
text = regex_replace(text, r"\d{16}", "[CARD]")
|
||||
modified.append(text)
|
||||
|
||||
# Block SQL in requests
|
||||
if input_type == "request":
|
||||
for text in inputs["texts"]:
|
||||
if contains_code_language(text, ["sql"]):
|
||||
return block("SQL injection blocked")
|
||||
|
||||
return modify(texts=modified)
|
||||
```
|
||||
|
||||
## Sandbox Restrictions
|
||||
|
||||
Custom code runs in a restricted environment:
|
||||
|
||||
- ❌ No `import` statements
|
||||
- ❌ No file I/O
|
||||
- ❌ No network access
|
||||
- ❌ No `exec()` or `eval()`
|
||||
- ✅ Only LiteLLM-provided primitives available
|
||||
|
||||
## Per-Request Usage
|
||||
|
||||
Enable guardrail per request:
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/chat/completions \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "gpt-4",
|
||||
"messages": [{"role": "user", "content": "Hello"}],
|
||||
"guardrails": ["block-ssn"]
|
||||
}'
|
||||
```
|
||||
|
||||
## Default On
|
||||
|
||||
Run guardrail on all requests:
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
guardrails:
|
||||
- guardrail_name: block-ssn
|
||||
litellm_params:
|
||||
guardrail: custom_code
|
||||
mode: pre_call
|
||||
default_on: true
|
||||
custom_code: |
|
||||
def apply_guardrail(inputs, request_data, input_type):
|
||||
...
|
||||
```
|
||||
|
|
@ -13,20 +13,26 @@ Cygnal returns a `violation` score between `0` and `1` (higher means more likely
|
|||
|
||||
### 1. Obtain Credentials
|
||||
|
||||
1. Create a Gray Swan account and generate a Cygnal API key.
|
||||
1. Log in to our Gray Swan platform and generate a Cygnal API key.
|
||||
|
||||
For existing customers, you should already have access to our [platform](https://platform.grayswan.ai).
|
||||
|
||||
For new users, please register at this [page](https://hubs.ly/Q03-sX1J0) and we are more than happy to give you an onboarding!
|
||||
|
||||
|
||||
2. Configure environment variables for the LiteLLM proxy host:
|
||||
|
||||
```bash
|
||||
export GRAYSWAN_API_KEY="your-grayswan-key"
|
||||
export GRAYSWAN_API_BASE="https://api.grayswan.ai"
|
||||
```
|
||||
```bash
|
||||
export GRAYSWAN_API_KEY="your-grayswan-key"
|
||||
export GRAYSWAN_API_BASE="https://api.grayswan.ai"
|
||||
```
|
||||
|
||||
### 2. Configure `config.yaml`
|
||||
|
||||
Add a guardrail entry that references the Gray Swan integration. Below is a balanced example that monitors both input and output but only blocks once the violation score reaches the configured threshold.
|
||||
Add a guardrail entry that references the Gray Swan integration. Below is our recommmended settings.
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
model_list: # this part is a standard litellm configuration for reference
|
||||
- model_name: openai/gpt-4.1-mini
|
||||
litellm_params:
|
||||
model: openai/gpt-4.1-mini
|
||||
|
|
@ -40,13 +46,14 @@ guardrails:
|
|||
api_key: os.environ/GRAYSWAN_API_KEY
|
||||
api_base: os.environ/GRAYSWAN_API_BASE # optional
|
||||
optional_params:
|
||||
on_flagged_action: monitor # or "block"
|
||||
on_flagged_action: passthrough # or "block" or "monitor"
|
||||
violation_threshold: 0.5 # score >= threshold is flagged
|
||||
reasoning_mode: hybrid # off | hybrid | thinking
|
||||
categories:
|
||||
safety: "Detect jailbreaks and policy violations"
|
||||
policy_id: "your-cygnal-policy-id"
|
||||
policy_id: "your-cygnal-policy-id" # Optional: Your Cygnal policy ID. Defaults to a content safety policy if empty.
|
||||
streaming_end_of_stream_only: true # For streaming API, only send the assembled message to Cygnal (post_call only). Defaults to false.
|
||||
default_on: true
|
||||
guardrail_timeout: 30 # Defaults to 30 seconds. Change accordingly.
|
||||
fail_open: true # Defaults to true; set to false to propagate guardrail errors.
|
||||
|
||||
general_settings:
|
||||
master_key: "your-litellm-master-key"
|
||||
|
|
@ -65,13 +72,13 @@ litellm --config config.yaml --port 4000
|
|||
|
||||
## Choosing Guardrail Modes
|
||||
|
||||
Gray Swan can run during `pre_call`, `during_call`, and `post_call` stages. Combine modes based on your latency and coverage requirements.
|
||||
Gray Swan can run during `pre_call`, `during_call`, and `post_call` stages. Combine modes based on your latency and coverage requirements.
|
||||
|
||||
| Mode | When it Runs | Protects | Typical Use Case |
|
||||
|--------------|-------------------|-----------------------|------------------|
|
||||
| `pre_call` | Before LLM call | User input only | Block prompt injection before it reaches the model |
|
||||
| `during_call`| Parallel to call | User input only | Low-latency monitoring without blocking |
|
||||
| `post_call` | After response | Full conversation | Scan output for policy violations, leaked secrets, or IPI |
|
||||
| `post_call` | After response | Model Outputs | Scan output for policy violations, leaked secrets, or IPI |
|
||||
|
||||
|
||||
When using `during_call` with `on_flagged_action: block` or `on_flagged_action: passthrough`:
|
||||
|
|
@ -81,87 +88,110 @@ When using `during_call` with `on_flagged_action: block` or `on_flagged_action:
|
|||
- The guardrail exception prevents the response from reaching the user, but **does not cancel the running LLM task**
|
||||
- This means you pay full LLM costs while returning an error/passthrough message to the user
|
||||
|
||||
**Recommendation:** For cost-sensitive applications, use `pre_call` and `post_call` instead of `during_call` for blocking or passthrough modes. Reserve `during_call` for `monitor` mode where you want low-latency logging without impacting the user experience.
|
||||
**Recommendation:** Use `pre_call` and `post_call` instead of `during_call` for `passthrough` (or `block`) `on_flagged_action` (see our recommended configuration above). Reserve `during_call` for `monitor` mode ONLY when you want low-latency logging without impacting the user experience.
|
||||
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="monitor" label="Monitor Only">
|
||||
---
|
||||
|
||||
```yaml
|
||||
guardrails:
|
||||
- guardrail_name: "cygnal-monitor-only"
|
||||
litellm_params:
|
||||
guardrail: grayswan
|
||||
mode: "during_call"
|
||||
api_key: os.environ/GRAYSWAN_API_KEY
|
||||
optional_params:
|
||||
on_flagged_action: monitor
|
||||
violation_threshold: 0.6
|
||||
default_on: true
|
||||
## Work with Claude Code
|
||||
|
||||
Follow the official litellm [guide](https://docs.litellm.ai/docs/tutorials/claude_responses_api) on setting up Claude Code with litellm, with the guardrail part mentioned above added to your litellm configuration. Cygnal natively supports coding agent policies defense. Define your own policy or use the provided coding policies on the platform. The example config we show above is also the recommended setup for Claude Code (with the `policy_id` replaced with an appropriate one).
|
||||
|
||||
---
|
||||
|
||||
## Per-request overrides via `extra_body`
|
||||
|
||||
You can override parts of the Gray Swan guardrail configuration on a per-request basis by passing `litellm_metadata.guardrails[*].grayswan.extra_body`.
|
||||
|
||||
`extra_body` is merged into the Cygnal request body and takes precedence over specific fields from `config.yaml`, which are `policy_id`, `violation_threshold`, and `reasoning_mode`.
|
||||
|
||||
If you include a `metadata` field inside `extra_body`, it is forwarded to the Cygnal API as-is under the request body's `metadata` field.
|
||||
|
||||
Example:
|
||||
|
||||
```bash
|
||||
curl -X POST "http://0.0.0.0:4000/v1/messages?beta=true" \
|
||||
-H "Authorization: Bearer token" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "openrouter/anthropic/claude-sonnet-4.5",
|
||||
"messages": [{"role": "user", "content": "hello"}],
|
||||
"litellm_metadata": {
|
||||
"guardrails": [
|
||||
{
|
||||
"cygnal-monitor": {
|
||||
"extra_body": {
|
||||
"policy_id": "specific policy id you want to use",
|
||||
"metadata": {
|
||||
"user": "health-check"
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
Best for visibility without blocking. Alerts are logged via LiteLLM’s standard logging callbacks.
|
||||
OpenAI client:
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="block-input" label="Block Input">
|
||||
```python
|
||||
from openai import OpenAI
|
||||
|
||||
```yaml
|
||||
guardrails:
|
||||
- guardrail_name: "cygnal-block-input"
|
||||
litellm_params:
|
||||
guardrail: grayswan
|
||||
mode: "pre_call"
|
||||
api_key: os.environ/GRAYSWAN_API_KEY
|
||||
optional_params:
|
||||
on_flagged_action: block
|
||||
violation_threshold: 0.4
|
||||
categories:
|
||||
pii: "Detect sensitive data"
|
||||
default_on: true
|
||||
client = OpenAI(api_key="anything", base_url="http://0.0.0.0:4000")
|
||||
|
||||
resp = client.responses.create(
|
||||
model="openrouter/anthropic/claude-sonnet-4.5",
|
||||
input="hello",
|
||||
extra_body={
|
||||
"litellm_metadata": {
|
||||
"guardrails": [
|
||||
{
|
||||
"cygnal-monitor": {
|
||||
"extra_body": {
|
||||
"policy_id": "69038214e5cdb6befc5e991e",
|
||||
"metadata": {"trace_id": "trace-123"},
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
},
|
||||
)
|
||||
```
|
||||
|
||||
Stops malicious or sensitive prompts before any tokens are generated.
|
||||
Anthropic client:
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="full-coverage" label="Full Coverage">
|
||||
```python
|
||||
from anthropic import Anthropic
|
||||
|
||||
```yaml
|
||||
guardrails:
|
||||
- guardrail_name: "cygnal-full-coverage"
|
||||
litellm_params:
|
||||
guardrail: grayswan
|
||||
mode: [pre_call, post_call]
|
||||
api_key: os.environ/GRAYSWAN_API_KEY
|
||||
optional_params:
|
||||
on_flagged_action: block
|
||||
violation_threshold: 0.5
|
||||
reasoning_mode: thinking
|
||||
policy_id: "policy-id-from-grayswan"
|
||||
default_on: true
|
||||
client = Anthropic(api_key="anything", base_url="http://0.0.0.0:4000")
|
||||
|
||||
resp = client.messages.create(
|
||||
model="openrouter/anthropic/claude-sonnet-4.5",
|
||||
max_tokens=256,
|
||||
messages=[{"role": "user", "content": "hello"}],
|
||||
extra_body={
|
||||
"litellm_metadata": {
|
||||
"guardrails": [
|
||||
{
|
||||
"cygnal-monitor": {
|
||||
"extra_body": {
|
||||
"policy_id": "69038214e5cdb6befc5e991e",
|
||||
"metadata": {"trace_id": "trace-123"},
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
},
|
||||
)
|
||||
```
|
||||
|
||||
Provides the strongest enforcement by inspecting both prompts and responses.
|
||||
Notes:
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="passthrough" label="Passthrough Mode">
|
||||
|
||||
```yaml
|
||||
guardrails:
|
||||
- guardrail_name: "cygnal-passthrough"
|
||||
litellm_params:
|
||||
guardrail: grayswan
|
||||
mode: [pre_call, post_call]
|
||||
api_key: os.environ/GRAYSWAN_API_KEY
|
||||
optional_params:
|
||||
on_flagged_action: passthrough
|
||||
violation_threshold: 0.5
|
||||
default_on: true
|
||||
```
|
||||
|
||||
Allows requests to proceed without raising a 400 error when content is flagged. Instead of blocking, the model response content is replaced with a detailed violation message including violation score, violated rules, and detection flags (mutation, IPI). **Supported Response Formats:** OpenAI chat/text completions, Anthropic Messages API. Other response types (embeddings, images, etc.) will log a warning and return unchanged.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
- The guardrail name (for example, `cygnal-monitor`) must match the `guardrail_name` in `config.yaml`.
|
||||
- Per-request guardrail overrides may require a premium license, depending on your proxy settings.
|
||||
|
||||
---
|
||||
|
||||
|
|
@ -170,9 +200,14 @@ Allows requests to proceed without raising a 400 error when content is flagged.
|
|||
| Parameter | Type | Description |
|
||||
|---------------------------------------|-----------------|-------------|
|
||||
| `api_key` | string | Gray Swan Cygnal API key. Reads from `GRAYSWAN_API_KEY` if omitted. |
|
||||
| `api_base` | string | Override for the Gray Swan API base URL. Defaults to `https://api.grayswan.ai` or `GRAYSWAN_API_BASE`. |
|
||||
| `mode` | string or list | Guardrail stages (`pre_call`, `during_call`, `post_call`). |
|
||||
| `optional_params.on_flagged_action` | string | `monitor` (log only), `block` (raise `HTTPException`), or `passthrough` (replace response content with violation message, no 400 error). |
|
||||
| `.optional_params.violation_threshold`| number (0-1) | Scores at or above this value are considered violations. |
|
||||
| `optional_params.violation_threshold` | number (0-1) | Scores at or above this value are considered violations. |
|
||||
| `optional_params.reasoning_mode` | string | `off`, `hybrid`, or `thinking`. Enables Cygnal's reasoning capabilities. |
|
||||
| `optional_params.categories` | object | Map of custom category names to descriptions. |
|
||||
| `optional_params.policy_id` | string | Gray Swan policy identifier. |
|
||||
| `guardrail_timeout` | number | Timeout in seconds for the Cygnal request. Defaults to 30. |
|
||||
| `fail_open` | boolean | If true, errors contacting Cygnal are logged and the request proceeds; if false, errors propagate. Defaults to treu. |
|
||||
| `streaming_end_of_stream_only` | boolean | For streaming `post_call`, only send the final assembled response to Cygnal. Defaults to false. |
|
||||
| `default_on` | boolean | Run the guardrail on every request by default. |
|
||||
|
|
|
|||
|
|
@ -69,6 +69,67 @@ router_settings:
|
|||
redis_port: 1992
|
||||
```
|
||||
|
||||
## Enforce Model Rate Limits
|
||||
|
||||
Strictly enforce RPM/TPM limits set on deployments. When limits are exceeded, requests are blocked **before** reaching the LLM provider with a `429 Too Many Requests` error.
|
||||
|
||||
:::info
|
||||
By default, `rpm` and `tpm` values are only used for **routing decisions** (picking deployments with capacity). With `enforce_model_rate_limits`, they become **hard limits**.
|
||||
:::
|
||||
|
||||
### Quick Start
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: openai/gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
rpm: 60 # 60 requests per minute
|
||||
tpm: 90000 # 90k tokens per minute
|
||||
|
||||
router_settings:
|
||||
optional_pre_call_checks:
|
||||
- enforce_model_rate_limits # 👈 Enables strict enforcement
|
||||
```
|
||||
|
||||
### How It Works
|
||||
|
||||
| Limit Type | Enforcement | Accuracy |
|
||||
|------------|-------------|----------|
|
||||
| **RPM** | Hard limit - blocked at exact threshold | 100% accurate |
|
||||
| **TPM** | Best-effort - may slightly exceed | Blocked when already over limit |
|
||||
|
||||
**Why TPM is best-effort:** Token count is unknown until the LLM responds. TPM is checked before each request (blocks if already over), and tracked after (adds actual tokens used).
|
||||
|
||||
### Error Response
|
||||
|
||||
```json
|
||||
{
|
||||
"error": {
|
||||
"message": "Model rate limit exceeded. RPM limit=60, current usage=60",
|
||||
"type": "rate_limit_error",
|
||||
"code": 429
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Response includes `retry-after: 60` header.
|
||||
|
||||
### Multi-Instance Deployment
|
||||
|
||||
For multiple LiteLLM proxy instances, add Redis to share rate limit state:
|
||||
|
||||
```yaml
|
||||
router_settings:
|
||||
optional_pre_call_checks:
|
||||
- enforce_model_rate_limits
|
||||
redis_host: redis.example.com
|
||||
redis_port: 6379
|
||||
redis_password: your-password
|
||||
```
|
||||
|
||||
|
||||
:::info
|
||||
Detailed information about [routing strategies can be found here](../routing)
|
||||
:::
|
||||
|
|
|
|||
58
docs/my-website/docs/proxy/request_tags.md
Normal file
58
docs/my-website/docs/proxy/request_tags.md
Normal file
|
|
@ -0,0 +1,58 @@
|
|||
# Request Tags for Spend Tracking
|
||||
|
||||
Add tags to model deployments to track spend by environment, AWS account, or any custom label.
|
||||
|
||||
Tags appear in the `request_tags` field of LiteLLM spend logs.
|
||||
|
||||
## Config Setup
|
||||
|
||||
Set tags on model deployments in `config.yaml`:
|
||||
|
||||
```yaml title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: azure/gpt-4-prod
|
||||
api_key: os.environ/AZURE_PROD_API_KEY
|
||||
api_base: https://prod.openai.azure.com/
|
||||
tags: ["AWS_IAM_PROD"] # 👈 Tag for production
|
||||
|
||||
- model_name: gpt-4-dev
|
||||
litellm_params:
|
||||
model: azure/gpt-4-dev
|
||||
api_key: os.environ/AZURE_DEV_API_KEY
|
||||
api_base: https://dev.openai.azure.com/
|
||||
tags: ["AWS_IAM_DEV"] # 👈 Tag for development
|
||||
```
|
||||
|
||||
## Make Request
|
||||
|
||||
Requests just specify the model - tags are automatically applied:
|
||||
|
||||
```bash
|
||||
curl -X POST 'http://0.0.0.0:4000/chat/completions' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-d '{
|
||||
"model": "gpt-4",
|
||||
"messages": [{"role": "user", "content": "Hello"}]
|
||||
}'
|
||||
```
|
||||
|
||||
## Spend Logs
|
||||
|
||||
The tag from the model config appears in `LiteLLM_SpendLogs`:
|
||||
|
||||
```json
|
||||
{
|
||||
"request_id": "chatcmpl-abc123",
|
||||
"request_tags": ["AWS_IAM_PROD"],
|
||||
"spend": 0.002,
|
||||
"model": "gpt-4"
|
||||
}
|
||||
```
|
||||
|
||||
## Related
|
||||
|
||||
- [Spend Tracking Overview](cost_tracking.md)
|
||||
- [Tag Budgets](tag_budgets.md) - Set budget limits per tag
|
||||
|
|
@ -37,6 +37,40 @@ general_settings:
|
|||
|
||||
<Image img={require('../../img/ui_request_logs_content.png')}/>
|
||||
|
||||
## Tracing Tools
|
||||
|
||||
View which tools were provided and called in your completion requests.
|
||||
|
||||
<Image img={require('../../img/ui_tools.png')}/>
|
||||
|
||||
**Example:** Make a completion request with tools:
|
||||
|
||||
```bash
|
||||
curl -X POST 'http://localhost:4000/chat/completions' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-d '{
|
||||
"model": "gpt-4",
|
||||
"messages": [{"role": "user", "content": "What is the weather?"}],
|
||||
"tools": [
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get the current weather",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {"type": "string"}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
Check the Logs page to see all tools provided and which ones were called.
|
||||
|
||||
## Stop storing Error Logs in DB
|
||||
|
||||
|
|
|
|||
|
|
@ -3,13 +3,15 @@ import TabItem from '@theme/TabItem';
|
|||
|
||||
# /realtime
|
||||
|
||||
Use this to loadbalance across Azure + OpenAI.
|
||||
Use this to loadbalance across Azure + OpenAI + xAI and more.
|
||||
|
||||
Supported Providers:
|
||||
- OpenAI
|
||||
- Azure
|
||||
- xAI ([see full docs](/docs/providers/xai_realtime))
|
||||
- Google AI Studio (Gemini)
|
||||
- Vertex AI
|
||||
- Bedrock
|
||||
|
||||
## Proxy Usage
|
||||
|
||||
|
|
@ -45,6 +47,21 @@ model_list:
|
|||
api_key: os.environ/OPENAI_API_KEY
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="xai" label="xAI Grok Voice Agent">
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: grok-voice-agent
|
||||
litellm_params:
|
||||
model: xai/grok-4-1-fast-non-reasoning
|
||||
api_key: os.environ/XAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
```
|
||||
|
||||
**[See full xAI Realtime documentation →](/docs/providers/xai_realtime)**
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
|
|
|||
|
|
@ -1588,11 +1588,13 @@ Get a slack webhook url from https://api.slack.com/messaging/webhooks
|
|||
Initialize an `AlertingConfig` and pass it to `litellm.Router`. The following code will trigger an alert because `api_key=bad-key` which is invalid
|
||||
|
||||
```python
|
||||
from litellm.router import AlertingConfig
|
||||
import litellm
|
||||
from litellm.router import Router
|
||||
from litellm.types.router import AlertingConfig
|
||||
import os
|
||||
import asyncio
|
||||
|
||||
router = litellm.Router(
|
||||
router = Router(
|
||||
model_list=[
|
||||
{
|
||||
"model_name": "gpt-3.5-turbo",
|
||||
|
|
@ -1603,17 +1605,28 @@ router = litellm.Router(
|
|||
}
|
||||
],
|
||||
alerting_config= AlertingConfig(
|
||||
alerting_threshold=10, # threshold for slow / hanging llm responses (in seconds). Defaults to 300 seconds
|
||||
webhook_url= os.getenv("SLACK_WEBHOOK_URL") # webhook you want to send alerts to
|
||||
alerting_threshold=10,
|
||||
webhook_url= "https:/..."
|
||||
),
|
||||
)
|
||||
try:
|
||||
await router.acompletion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "Hey, how's it going?"}],
|
||||
)
|
||||
except:
|
||||
pass
|
||||
|
||||
async def main():
|
||||
print(f"\n=== Configuration ===")
|
||||
print(f"Slack logger exists: {router.slack_alerting_logger is not None}")
|
||||
|
||||
try:
|
||||
await router.acompletion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "Hey, how's it going?"}],
|
||||
)
|
||||
except Exception as e:
|
||||
print(f"\n=== Exception caught ===")
|
||||
print(f"Waiting 10 seconds for alerts to be sent via periodic flush...")
|
||||
await asyncio.sleep(10)
|
||||
print(f"\n=== After waiting ===")
|
||||
print(f"Alert should have been sent to Slack!")
|
||||
|
||||
asyncio.run(main())
|
||||
```
|
||||
|
||||
## Track cost for Azure Deployments
|
||||
|
|
|
|||
113
docs/my-website/docs/troubleshoot/prisma_migrations.md
Normal file
113
docs/my-website/docs/troubleshoot/prisma_migrations.md
Normal file
|
|
@ -0,0 +1,113 @@
|
|||
# Troubleshooting Prisma Migration Errors
|
||||
|
||||
Common Prisma migration issues encountered when upgrading or downgrading LiteLLM proxy versions, and how to fix them.
|
||||
|
||||
## How Prisma Migrations Work in LiteLLM
|
||||
|
||||
- LiteLLM uses [Prisma](https://www.prisma.io/) to manage its PostgreSQL database schema.
|
||||
- Migration history is tracked in the `_prisma_migrations` table in your database.
|
||||
- When LiteLLM starts, it runs `prisma migrate deploy` to apply any new migrations.
|
||||
- Upgrading LiteLLM applies all migrations added since your last applied version.
|
||||
|
||||
## Common Errors
|
||||
|
||||
### 1. `relation "X" does not exist`
|
||||
|
||||
**Example error:**
|
||||
|
||||
```
|
||||
ERROR: relation "LiteLLM_DeletedTeamTable" does not exist
|
||||
Migration: 20260116142756_update_deleted_keys_teams_table_routing_settings
|
||||
```
|
||||
|
||||
**Cause:** This typically happens after a version rollback. The `_prisma_migrations` table still records migrations from the newer version as "applied," but the underlying database tables were modified, dropped, or never fully created.
|
||||
|
||||
**How to fix:**
|
||||
|
||||
#### Step 1 — Delete the failed migration entry and restart
|
||||
|
||||
Remove the problematic migration from the history so it can be re-applied:
|
||||
|
||||
```sql
|
||||
-- View recent migrations
|
||||
SELECT migration_name, finished_at, rolled_back_at, logs
|
||||
FROM "_prisma_migrations"
|
||||
ORDER BY started_at DESC
|
||||
LIMIT 10;
|
||||
|
||||
-- Delete the failed migration entry
|
||||
DELETE FROM "_prisma_migrations"
|
||||
WHERE migration_name = '<failed_migration_name>';
|
||||
```
|
||||
|
||||
After deleting the entry, restart LiteLLM — it will re-apply the migration on startup.
|
||||
|
||||
#### Step 2 — If that doesn't work, use `prisma db push`
|
||||
|
||||
If deleting the migration entry and restarting doesn't resolve the issue, sync the schema directly:
|
||||
|
||||
```bash
|
||||
DATABASE_URL="<your_database_url>" prisma db push
|
||||
```
|
||||
|
||||
This bypasses migration history and forces the database schema to match the Prisma schema.
|
||||
|
||||
---
|
||||
|
||||
### 2. `New migrations cannot be applied before the error is recovered from`
|
||||
|
||||
**Cause:** A previous migration failed (recorded with an error in `_prisma_migrations`), and Prisma refuses to apply any new migrations until the failure is resolved.
|
||||
|
||||
**How to fix:**
|
||||
|
||||
1. Find the failed migration:
|
||||
|
||||
```sql
|
||||
SELECT migration_name, finished_at, rolled_back_at, logs
|
||||
FROM "_prisma_migrations"
|
||||
WHERE finished_at IS NULL OR rolled_back_at IS NOT NULL
|
||||
ORDER BY started_at DESC;
|
||||
```
|
||||
|
||||
2. Delete the failed entry and restart LiteLLM:
|
||||
|
||||
```sql
|
||||
DELETE FROM "_prisma_migrations"
|
||||
WHERE migration_name = '<failed_migration_name>';
|
||||
```
|
||||
|
||||
3. If that doesn't work, use `prisma db push`:
|
||||
|
||||
```bash
|
||||
DATABASE_URL="<your_database_url>" prisma db push
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
### 3. Migration state mismatch after version rollback
|
||||
|
||||
**Cause:** You upgraded to version X (new migrations applied), rolled back to version Y, then upgraded again. The `_prisma_migrations` table has stale entries for migrations that were partially applied or correspond to a schema state that no longer exists.
|
||||
|
||||
**Fix:**
|
||||
|
||||
1. Inspect the migration table for problematic entries:
|
||||
|
||||
```sql
|
||||
SELECT migration_name, started_at, finished_at, rolled_back_at, logs
|
||||
FROM "_prisma_migrations"
|
||||
ORDER BY started_at DESC
|
||||
LIMIT 20;
|
||||
```
|
||||
|
||||
2. For each migration that shouldn't be there (i.e., from the version you rolled back from), delete the entry:
|
||||
```sql
|
||||
DELETE FROM "_prisma_migrations" WHERE migration_name = '<migration_name>';
|
||||
```
|
||||
|
||||
3. Restart LiteLLM to re-run migrations.
|
||||
|
||||
4. If that doesn't work, use `prisma db push`:
|
||||
|
||||
```bash
|
||||
DATABASE_URL="<your_database_url>" prisma db push
|
||||
```
|
||||
129
docs/my-website/docs/tutorials/claude_code_beta_headers.md
Normal file
129
docs/my-website/docs/tutorials/claude_code_beta_headers.md
Normal file
|
|
@ -0,0 +1,129 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Claude Code - Fixing Invalid Beta Header Errors
|
||||
|
||||
When using Claude Code with LiteLLM and non-Anthropic providers (Bedrock, Azure AI, Vertex AI), you may encounter "invalid beta header" errors. This guide explains how to fix these errors locally or contribute a fix to LiteLLM.
|
||||
|
||||
## What Are Beta Headers?
|
||||
|
||||
Anthropic uses beta headers to enable experimental features in Claude. When you use Claude Code, it may send beta headers like:
|
||||
|
||||
```
|
||||
anthropic-beta: prompt-caching-scope-2026-01-05,advanced-tool-use-2025-11-20
|
||||
```
|
||||
|
||||
However, not all providers support all Anthropic beta features. When an unsupported beta header is sent to a provider, you'll see an error.
|
||||
|
||||
## Common Error Message
|
||||
|
||||
```bash
|
||||
Error: The model returned the following errors: invalid beta flag
|
||||
```
|
||||
|
||||
## How LiteLLM Handles Beta Headers
|
||||
|
||||
LiteLLM automatically filters out unsupported beta headers using a configuration file:
|
||||
|
||||
```
|
||||
litellm/litellm/anthropic_beta_headers_config.json
|
||||
```
|
||||
|
||||
This JSON file lists which beta headers are **unsupported** for each provider. Headers not in the unsupported list are passed through to the provider.
|
||||
|
||||
## Quick Fix: Update Config Locally
|
||||
|
||||
If you encounter an invalid beta header error, you can fix it immediately by updating the config file locally.
|
||||
|
||||
### Step 1: Locate the Config File
|
||||
|
||||
Find the file in your LiteLLM installation:
|
||||
|
||||
```bash
|
||||
# If installed via pip
|
||||
cd $(python -c "import litellm; import os; print(os.path.dirname(litellm.__file__))")
|
||||
|
||||
# The config file is at:
|
||||
# litellm/anthropic_beta_headers_config.json
|
||||
```
|
||||
|
||||
### Step 2: Add the Unsupported Header
|
||||
|
||||
Open `anthropic_beta_headers_config.json` and add the problematic header to the appropriate provider's list:
|
||||
|
||||
```json title="anthropic_beta_headers_config.json"
|
||||
{
|
||||
"description": "Unsupported Anthropic beta headers for each provider. Headers listed here will be dropped. Headers not listed are passed through as-is.",
|
||||
"anthropic": [],
|
||||
"azure_ai": [],
|
||||
"bedrock_converse": [
|
||||
"prompt-caching-scope-2026-01-05",
|
||||
"bash_20250124",
|
||||
"bash_20241022",
|
||||
"text_editor_20250124",
|
||||
"text_editor_20241022",
|
||||
"compact-2026-01-12",
|
||||
"advanced-tool-use-2025-11-20",
|
||||
"web-fetch-2025-09-10",
|
||||
"code-execution-2025-08-25",
|
||||
"skills-2025-10-02",
|
||||
"files-api-2025-04-14"
|
||||
],
|
||||
"bedrock": [
|
||||
"advanced-tool-use-2025-11-20",
|
||||
"prompt-caching-scope-2026-01-05",
|
||||
"structured-outputs-2025-11-13",
|
||||
"web-fetch-2025-09-10",
|
||||
"code-execution-2025-08-25",
|
||||
"skills-2025-10-02",
|
||||
"files-api-2025-04-14"
|
||||
],
|
||||
"vertex_ai": [
|
||||
"prompt-caching-scope-2026-01-05"
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
### Step 3: Restart Your Application
|
||||
|
||||
After updating the config file, restart your LiteLLM proxy or application:
|
||||
|
||||
```bash
|
||||
# If using LiteLLM proxy
|
||||
litellm --config config.yaml
|
||||
|
||||
# If using Python SDK
|
||||
# Just restart your Python application
|
||||
```
|
||||
|
||||
The updated configuration will be loaded automatically.
|
||||
|
||||
## Contributing a Fix to LiteLLM
|
||||
|
||||
Help the community by contributing your fix! If your local changes work, please raise a PR with the addition of the header and we will merge it.
|
||||
|
||||
|
||||
## How Beta Header Filtering Works
|
||||
|
||||
When you make a request through LiteLLM:
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant CC as Claude Code
|
||||
participant LP as LiteLLM
|
||||
participant Config as Beta Headers Config
|
||||
participant Provider as Provider (Bedrock/Azure/etc)
|
||||
|
||||
CC->>LP: Request with beta headers
|
||||
Note over CC,LP: anthropic-beta: header1,header2,header3
|
||||
|
||||
LP->>Config: Load unsupported headers for provider
|
||||
Config-->>LP: Returns unsupported list
|
||||
|
||||
Note over LP: Filter headers:<br/>- Remove unsupported<br/>- Keep supported
|
||||
|
||||
LP->>Provider: Request with filtered headers
|
||||
Note over LP,Provider: anthropic-beta: header2<br/>(header1, header3 removed)
|
||||
|
||||
Provider-->>LP: Success response
|
||||
LP-->>CC: Response
|
||||
```
|
||||
99
docs/my-website/docs/tutorials/copilotkit_sdk.md
Normal file
99
docs/my-website/docs/tutorials/copilotkit_sdk.md
Normal file
|
|
@ -0,0 +1,99 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# CopilotKit SDK with LiteLLM
|
||||
|
||||
Use CopilotKit SDK with any LLM provider through LiteLLM Proxy.
|
||||
|
||||
> **Note:** CopilotKit SDK integration with LiteLLM Proxy works with LiteLLM v1.81.7-nightly or higher.
|
||||
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Add Model to Config
|
||||
|
||||
```yaml title="config.yaml"
|
||||
model_list:
|
||||
- model_name: claude-sonnet-4-5
|
||||
litellm_params:
|
||||
model: "anthropic/claude-sonnet-4-5-20250514-v1:0"
|
||||
api_key: "os.environ/ANTHROPIC_API_KEY"
|
||||
```
|
||||
|
||||
### 2. Start LiteLLM Proxy
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
### 3. Use CopilotKit SDK
|
||||
|
||||
```typescript
|
||||
import OpenAI from "openai";
|
||||
import {
|
||||
CopilotRuntime,
|
||||
OpenAIAdapter,
|
||||
copilotRuntimeNextJSAppRouterEndpoint,
|
||||
} from "@copilotkit/runtime";
|
||||
import { NextRequest } from "next/server";
|
||||
|
||||
const model = "claude-sonnet-4-5";
|
||||
|
||||
const openai = new OpenAI({
|
||||
apiKey: process.env.OPENAI_API_KEY || "sk-12345",
|
||||
baseURL: process.env.OPENAI_BASE_URL || "http://localhost:4000/v1",
|
||||
});
|
||||
|
||||
const serviceAdapter = new OpenAIAdapter({ openai, model });
|
||||
const runtime = new CopilotRuntime();
|
||||
|
||||
export const POST = async (req: NextRequest) => {
|
||||
const { handleRequest } = copilotRuntimeNextJSAppRouterEndpoint({
|
||||
runtime,
|
||||
serviceAdapter,
|
||||
endpoint: "/api/copilotkit",
|
||||
});
|
||||
return handleRequest(req);
|
||||
};
|
||||
```
|
||||
|
||||
### 4. Test
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:3000/api/copilotkit \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"method": "agent/run",
|
||||
"params": {
|
||||
"agentId": "default"
|
||||
},
|
||||
"runId": "your_run_id",
|
||||
"threadId": "your_thread_id",
|
||||
"runId": ""your_run_id"",
|
||||
"tools": [],
|
||||
"context": [],
|
||||
"forwardedProps": {},
|
||||
"state": {},
|
||||
"messages": [
|
||||
{
|
||||
"id": "166e573e-f7c6-4c0f-8685-04dbefec18be",
|
||||
"content": "Hi",
|
||||
"role": "user"
|
||||
}
|
||||
]
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
## Environment Variables
|
||||
|
||||
| Variable | Value | Description |
|
||||
|----------|-------|-------------|
|
||||
| `OPENAI_API_KEY` | `sk-12345` | Your LiteLLM API key |
|
||||
| `OPENAI_BASE_URL` | `http://localhost:4000/v1` | LiteLLM proxy URL |
|
||||
|
||||
|
||||
## Related Resources
|
||||
|
||||
- [CopilotKit Documentation](https://docs.copilotkit.ai)
|
||||
- [LiteLLM Proxy Quick Start](../proxy/quick_start)
|
||||
190
docs/my-website/docs/tutorials/livekit_xai_realtime.md
Normal file
190
docs/my-website/docs/tutorials/livekit_xai_realtime.md
Normal file
|
|
@ -0,0 +1,190 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# LiveKit xAI Realtime Voice Agent
|
||||
|
||||
Use LiveKit's xAI Grok Voice Agent plugin with LiteLLM Proxy to build low-latency voice AI agents.
|
||||
|
||||
The LiveKit Agents framework provides tools for building real-time voice and video AI applications. By routing through LiteLLM Proxy, you get unified access to multiple realtime voice providers, cost tracking, rate limiting, and more.
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Install Dependencies
|
||||
|
||||
```bash
|
||||
pip install livekit-agents[xai]
|
||||
```
|
||||
|
||||
### 2. Start LiteLLM Proxy
|
||||
|
||||
Create a config file with your xAI realtime model:
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
model_list:
|
||||
- model_name: grok-voice-agent
|
||||
litellm_params:
|
||||
model: xai/grok-2-vision-1212
|
||||
api_key: os.environ/XAI_API_KEY
|
||||
model_info:
|
||||
mode: realtime
|
||||
|
||||
litellm_settings:
|
||||
drop_params: True
|
||||
|
||||
general_settings:
|
||||
master_key: sk-1234 # Change this to a secure key
|
||||
```
|
||||
|
||||
Start the proxy:
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml --port 4000
|
||||
```
|
||||
|
||||
### 3. Configure LiveKit xAI Plugin
|
||||
|
||||
Point LiveKit's xAI plugin to your LiteLLM proxy:
|
||||
|
||||
```python
|
||||
from livekit.plugins import xai
|
||||
|
||||
# Configure xAI to use LiteLLM proxy
|
||||
model = xai.realtime.RealtimeModel(
|
||||
voice="ara", # Voice option
|
||||
api_key="sk-1234", # Your LiteLLM proxy master key
|
||||
base_url="http://localhost:4000", # LiteLLM proxy URL
|
||||
)
|
||||
```
|
||||
|
||||
## Complete Example
|
||||
|
||||
Here's a complete working example:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="python" label="Python Client">
|
||||
|
||||
```python
|
||||
#!/usr/bin/env python3
|
||||
"""
|
||||
Simple xAI realtime voice agent through LiteLLM proxy.
|
||||
"""
|
||||
import asyncio
|
||||
import json
|
||||
import websockets
|
||||
|
||||
PROXY_URL = "ws://localhost:4000/v1/realtime"
|
||||
API_KEY = "sk-1234"
|
||||
MODEL = "grok-voice-agent"
|
||||
|
||||
async def run_voice_agent():
|
||||
"""Connect to xAI realtime API through LiteLLM proxy"""
|
||||
url = f"{PROXY_URL}?model={MODEL}"
|
||||
headers = {"Authorization": f"Bearer {API_KEY}"}
|
||||
|
||||
async with websockets.connect(url, extra_headers=headers) as ws:
|
||||
# Wait for initial connection event
|
||||
initial = json.loads(await ws.recv())
|
||||
print(f"✅ Connected: {initial['type']}")
|
||||
|
||||
# Send user message
|
||||
await ws.send(json.dumps({
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{
|
||||
"type": "input_text",
|
||||
"text": "Hello! Tell me a joke."
|
||||
}]
|
||||
}
|
||||
}))
|
||||
|
||||
# Request response
|
||||
await ws.send(json.dumps({
|
||||
"type": "response.create",
|
||||
"response": {"modalities": ["text", "audio"]}
|
||||
}))
|
||||
|
||||
# Collect response
|
||||
transcript = []
|
||||
async for message in ws:
|
||||
event = json.loads(message)
|
||||
|
||||
# Capture text response
|
||||
if event['type'] == 'response.output_audio_transcript.delta':
|
||||
transcript.append(event['delta'])
|
||||
print(event['delta'], end='', flush=True)
|
||||
|
||||
# Done when response completes
|
||||
elif event['type'] == 'response.done':
|
||||
break
|
||||
|
||||
print(f"\n\n✅ Full response: {''.join(transcript)}")
|
||||
|
||||
if __name__ == "__main__":
|
||||
asyncio.run(run_voice_agent())
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="livekit" label="LiveKit Agent">
|
||||
|
||||
```python
|
||||
from livekit.agents import Agent, AgentSession, WorkerOptions, cli
|
||||
from livekit.plugins import xai
|
||||
|
||||
class VoiceAgent(Agent):
|
||||
def __init__(self):
|
||||
super().__init__(
|
||||
instructions="You are a helpful voice assistant.",
|
||||
llm=xai.realtime.RealtimeModel(
|
||||
voice="ara",
|
||||
api_key="sk-1234",
|
||||
base_url="http://localhost:4000",
|
||||
),
|
||||
)
|
||||
|
||||
if __name__ == "__main__":
|
||||
cli.run_app(
|
||||
WorkerOptions(
|
||||
agent_factory=VoiceAgent,
|
||||
)
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Running the Example
|
||||
|
||||
1. **Start LiteLLM Proxy** (if not already running):
|
||||
```bash
|
||||
litellm --config config.yaml --port 4000
|
||||
```
|
||||
|
||||
2. **Run the example**:
|
||||
```bash
|
||||
python your_script.py
|
||||
```
|
||||
|
||||
## Expected Output
|
||||
|
||||
```
|
||||
✅ Connected: conversation.created
|
||||
Hello! Here's a joke for you: Why don't scientists trust atoms?
|
||||
Because they make up everything!
|
||||
|
||||
✅ Full response: Hello! Here's a joke for you: Why don't scientists trust atoms? Because they make up everything!
|
||||
```
|
||||
|
||||
|
||||
## Complete Working Example
|
||||
|
||||
**[LiveKit Agent SDK Cookbook](https://github.com/BerriAI/litellm/tree/main/cookbook/livekit_agent_sdk)**
|
||||
|
||||
|
||||
## Learn More
|
||||
|
||||
- [xAI Realtime API](/docs/providers/xai_realtime)
|
||||
- [LiveKit xAI Plugin](https://docs.livekit.io/agents/models/realtime/plugins/xai/)
|
||||
- [LiteLLM Realtime API](/docs/realtime)
|
||||
BIN
docs/my-website/img/okta_access_policies.png
Normal file
BIN
docs/my-website/img/okta_access_policies.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 82 KiB |
BIN
docs/my-website/img/okta_authorization_server.png
Normal file
BIN
docs/my-website/img/okta_authorization_server.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 52 KiB |
BIN
docs/my-website/img/okta_client_credentials.png
Normal file
BIN
docs/my-website/img/okta_client_credentials.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 64 KiB |
BIN
docs/my-website/img/okta_redirect_uri.png
Normal file
BIN
docs/my-website/img/okta_redirect_uri.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 60 KiB |
BIN
docs/my-website/img/okta_security_api.png
Normal file
BIN
docs/my-website/img/okta_security_api.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 38 KiB |
BIN
docs/my-website/img/ui_tools.png
Normal file
BIN
docs/my-website/img/ui_tools.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 420 KiB |
384
docs/my-website/release_notes/v1.81.6.md
Normal file
384
docs/my-website/release_notes/v1.81.6.md
Normal file
|
|
@ -0,0 +1,384 @@
|
|||
---
|
||||
title: "v1.81.6 - Logs v2 with Tool Call Tracing"
|
||||
slug: "v1-81-6"
|
||||
date: 2026-01-31T00:00:00
|
||||
authors:
|
||||
- name: Krrish Dholakia
|
||||
title: CEO, LiteLLM
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: CTO, LiteLLM
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
## Deploy this version
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import Image from '@theme/IdealImage';
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="docker" label="Docker">
|
||||
|
||||
```bash
|
||||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
docker.litellm.ai/berriai/litellm:main-v1.81.6
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="pip" label="Pip">
|
||||
|
||||
```bash
|
||||
pip install litellm==1.81.6
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Key Highlights
|
||||
|
||||
Logs View v2 with Tool Call Tracing - Redesigned logs interface with side panel, structured tool visualization, and error message search for faster debugging.
|
||||
|
||||
Let's dive in.
|
||||
|
||||
### Logs View v2 with Tool Call Tracing
|
||||
|
||||
This release introduces comprehensive tool call tracing through LiteLLM's redesigned Logs View v2, enabling developers to debug and monitor AI agent workflows in production environments seamlessly.
|
||||
|
||||
This means you can now onboard use cases like tracing complex multi-step agent interactions, debugging tool execution failures, and monitoring MCP server calls while maintaining full visibility into request/response payloads with syntax highlighting.
|
||||
|
||||
Developers can access the new Logs View through LiteLLM's UI to inspect tool calls in structured format, search logs by error messages or request patterns, and correlate agent activities across sessions with collapsible side panel views.
|
||||
|
||||
{/* TODO: Add image from Slack (group_7219.png) - save as logs_v2_tool_tracing.png */}
|
||||
{/* <Image img={require('../../img/release_notes/logs_v2_tool_tracing.png')} style={{ maxWidth: '800px', width: '100%' }} /> */}
|
||||
|
||||
[Get Started](../../docs/proxy/ui_logs)
|
||||
|
||||
## New Models / Updated Models
|
||||
|
||||
#### New Model Support
|
||||
|
||||
| Provider | Model | Context Window | Input ($/1M tokens) | Output ($/1M tokens) | Features |
|
||||
| -------- | ----- | -------------- | ------------------- | -------------------- | -------- |
|
||||
| AWS Bedrock | `amazon.nova-2-pro-preview-20251202-v1:0` | 1M | $2.19 | $17.50 | Chat completions, vision, video, PDF, function calling, prompt caching, reasoning |
|
||||
| Google Vertex AI | `gemini-robotics-er-1.5-preview` | 1M | $0.30 | $2.50 | Chat completions, multimodal (text, image, video, audio), function calling, reasoning |
|
||||
| OpenRouter | `openrouter/xiaomi/mimo-v2-flash` | 262K | $0.09 | $0.29 | Chat completions, function calling, reasoning |
|
||||
| OpenRouter | `openrouter/moonshotai/kimi-k2.5` | - | - | - | Chat completions |
|
||||
| OpenRouter | `openrouter/z-ai/glm-4.7` | 202K | $0.40 | $1.50 | Chat completions, vision, function calling, reasoning |
|
||||
|
||||
#### Features
|
||||
|
||||
- **[AWS Bedrock](../../docs/providers/bedrock)**
|
||||
- Messages API Bedrock Converse caching and PDF support - [PR #19785](https://github.com/BerriAI/litellm/pull/19785)
|
||||
- Translate advanced-tool-use to Bedrock-specific headers for Claude Opus 4.5 - [PR #19841](https://github.com/BerriAI/litellm/pull/19841)
|
||||
- Support tool search header translation for Sonnet 4.5 - [PR #19871](https://github.com/BerriAI/litellm/pull/19871)
|
||||
- Filter unsupported beta headers for AWS Bedrock Invoke API - [PR #19877](https://github.com/BerriAI/litellm/pull/19877)
|
||||
- Nova grounding improvements - [PR #19598](https://github.com/BerriAI/litellm/pull/19598), [PR #20159](https://github.com/BerriAI/litellm/pull/20159)
|
||||
|
||||
- **[Anthropic](../../docs/providers/anthropic)**
|
||||
- Remove explicit cache_control null in tool_result content - [PR #19919](https://github.com/BerriAI/litellm/pull/19919)
|
||||
- Fix tool handling - [PR #19805](https://github.com/BerriAI/litellm/pull/19805)
|
||||
|
||||
- **[Google Gemini / Vertex AI](../../docs/providers/gemini)**
|
||||
- Add Gemini Robotics-ER 1.5 preview support - [PR #19845](https://github.com/BerriAI/litellm/pull/19845)
|
||||
- Support file retrieval in GoogleAIStudioFilesHandle - [PR #20018](https://github.com/BerriAI/litellm/pull/20018)
|
||||
- Add /delete endpoint support - [PR #20055](https://github.com/BerriAI/litellm/pull/20055)
|
||||
- Add custom_llm_provider as gemini translation - [PR #19988](https://github.com/BerriAI/litellm/pull/19988)
|
||||
- Subtract implicit cached tokens from text_tokens for correct cost calculation - [PR #19775](https://github.com/BerriAI/litellm/pull/19775)
|
||||
- Remove unsupported prompt-caching-scope-2026-01-05 header for vertex ai - [PR #20058](https://github.com/BerriAI/litellm/pull/20058)
|
||||
- Add disable flag for anthropic gemini cache translation - [PR #20052](https://github.com/BerriAI/litellm/pull/20052)
|
||||
- Convert image URLs to base64 in tool messages for Anthropic on Vertex AI - [PR #19896](https://github.com/BerriAI/litellm/pull/19896)
|
||||
|
||||
- **[xAI](../../docs/providers/xai)**
|
||||
- Add grok reasoning content support - [PR #19850](https://github.com/BerriAI/litellm/pull/19850)
|
||||
- Add websearch params support for Responses API - [PR #19915](https://github.com/BerriAI/litellm/pull/19915)
|
||||
- Add routing of xai chat completions to responses when web search options is present - [PR #20051](https://github.com/BerriAI/litellm/pull/20051)
|
||||
- Correct cached token cost calculation - [PR #19772](https://github.com/BerriAI/litellm/pull/19772)
|
||||
|
||||
- **[Azure OpenAI](../../docs/providers/azure)**
|
||||
- Use generic cost calculator for audio token pricing - [PR #19771](https://github.com/BerriAI/litellm/pull/19771)
|
||||
- Allow tool_choice for Azure GPT-5 chat models - [PR #19813](https://github.com/BerriAI/litellm/pull/19813)
|
||||
- Set gpt-5.2-codex mode to responses for Azure and OpenRouter - [PR #19770](https://github.com/BerriAI/litellm/pull/19770)
|
||||
|
||||
- **[OpenAI](../../docs/providers/openai)**
|
||||
- Fix max_input_tokens for gpt-5.2-codex - [PR #20009](https://github.com/BerriAI/litellm/pull/20009)
|
||||
- Fix gpt-image-1.5 cost calculation not including output image tokens - [PR #19515](https://github.com/BerriAI/litellm/pull/19515)
|
||||
|
||||
- **[Hosted VLLM](../../docs/providers/vllm)**
|
||||
- Support thinking parameter in anthropic_messages() and .completion() - [PR #19787](https://github.com/BerriAI/litellm/pull/19787)
|
||||
- Route through base_llm_http_handler to support ssl_verify - [PR #19893](https://github.com/BerriAI/litellm/pull/19893)
|
||||
- Fix vllm embedding format - [PR #20056](https://github.com/BerriAI/litellm/pull/20056)
|
||||
|
||||
- **[OCI GenAI](../../docs/providers/oci)**
|
||||
- Serialize imageUrl as object for OCI GenAI API - [PR #19661](https://github.com/BerriAI/litellm/pull/19661)
|
||||
|
||||
- **[Volcengine](../../docs/providers/volcano)**
|
||||
- Add context for volcengine models (deepseek-v3-2, glm-4-7, kimi-k2-thinking) - [PR #19335](https://github.com/BerriAI/litellm/pull/19335)
|
||||
|
||||
- **[Chinese Providers](../../docs/providers/)**
|
||||
- Add prompt caching and reasoning support for MiniMax, GLM, Xiaomi - [PR #19924](https://github.com/BerriAI/litellm/pull/19924)
|
||||
|
||||
- **[Vercel AI Gateway](../../docs/providers/vercel_ai_gateway)**
|
||||
- Add embeddings support - [PR #19660](https://github.com/BerriAI/litellm/pull/19660)
|
||||
|
||||
### Bug Fixes
|
||||
|
||||
- **[Google](../../docs/providers/gemini)**
|
||||
- Fix gemini-robotics-er-1.5-preview entry - [PR #19974](https://github.com/BerriAI/litellm/pull/19974)
|
||||
|
||||
- **General**
|
||||
- Fix output_tokens_details.reasoning_tokens None - [PR #19914](https://github.com/BerriAI/litellm/pull/19914)
|
||||
- Fix stream_chunk_builder to preserve images from streaming chunks - [PR #19654](https://github.com/BerriAI/litellm/pull/19654)
|
||||
- Fix aspectRatio mapping in image edit - [PR #20053](https://github.com/BerriAI/litellm/pull/20053)
|
||||
- Handle unknown models in Azure AI cost calculator - [PR #20150](https://github.com/BerriAI/litellm/pull/20150)
|
||||
|
||||
- **[GigaChat](../../docs/providers/gigachat)**
|
||||
- Ensure function content is valid JSON - [PR #19232](https://github.com/BerriAI/litellm/pull/19232)
|
||||
|
||||
## LLM API Endpoints
|
||||
|
||||
#### Features
|
||||
|
||||
- **[Messages API (/messages)](../../docs/mcp)**
|
||||
- Add LiteLLM x Claude Agent SDK Integration - [PR #20035](https://github.com/BerriAI/litellm/pull/20035)
|
||||
|
||||
- **[A2A / MCP Gateway API (/a2a, /mcp)](../../docs/mcp)**
|
||||
- Add A2A agent header-based context propagation support - [PR #19504](https://github.com/BerriAI/litellm/pull/19504)
|
||||
- Enable progress notifications for MCP tool calls - [PR #19809](https://github.com/BerriAI/litellm/pull/19809)
|
||||
- Fix support for non-standard MCP URL patterns - [PR #19738](https://github.com/BerriAI/litellm/pull/19738)
|
||||
- Add backward compatibility for legacy A2A card formats (/.well-known/agent.json) - [PR #19949](https://github.com/BerriAI/litellm/pull/19949)
|
||||
- Add support for agent parameter in /interactions endpoint - [PR #19866](https://github.com/BerriAI/litellm/pull/19866)
|
||||
|
||||
- **[Responses API (/responses)](../../docs/response_api)**
|
||||
- Fix custom_llm_provider for provider-specific params - [PR #19798](https://github.com/BerriAI/litellm/pull/19798)
|
||||
- Extract input tokens details as dict in ResponseAPILoggingUtils - [PR #20046](https://github.com/BerriAI/litellm/pull/20046)
|
||||
|
||||
- **[Batch API (/batches)](../../docs/batches)**
|
||||
- Fix /batches to return encoded ids (from managed objects table) - [PR #19040](https://github.com/BerriAI/litellm/pull/19040)
|
||||
- Fix Batch and File user level permissions - [PR #19981](https://github.com/BerriAI/litellm/pull/19981)
|
||||
- Add cost tracking and usage object in retrieve_batch call type - [PR #19986](https://github.com/BerriAI/litellm/pull/19986)
|
||||
|
||||
- **[Embeddings API (/embeddings)](../../docs/embedding/supported_embedding)**
|
||||
- Add supported input formats documentation - [PR #20073](https://github.com/BerriAI/litellm/pull/20073)
|
||||
|
||||
- **[RAG API (/rag/ingest, /vector_store)](../../docs/rag_ingest)**
|
||||
- Add UI for /rag/ingest API - Upload docs, pdfs etc to create vector stores - [PR #19822](https://github.com/BerriAI/litellm/pull/19822)
|
||||
- Add support for using S3 Vectors as Vector Store Provider - [PR #19888](https://github.com/BerriAI/litellm/pull/19888)
|
||||
- Add s3_vectors as provider on /vector_store/search API + UI for creating + PDF support - [PR #19895](https://github.com/BerriAI/litellm/pull/19895)
|
||||
- Add permission management for users and teams on Vector Stores - [PR #19972](https://github.com/BerriAI/litellm/pull/19972)
|
||||
- Enable router support for completions in RAG query pipeline - [PR #19550](https://github.com/BerriAI/litellm/pull/19550)
|
||||
|
||||
- **[Search API (/search)](../../docs/search)**
|
||||
- Add /list endpoint to list what search tools exist in router - [PR #19969](https://github.com/BerriAI/litellm/pull/19969)
|
||||
- Fix router search tools v2 integration - [PR #19840](https://github.com/BerriAI/litellm/pull/19840)
|
||||
|
||||
- **[Passthrough Endpoints (/\{provider\}_passthrough)](../../docs/pass_through/intro)**
|
||||
- Add /openai_passthrough route for OpenAI passthrough requests - [PR #19989](https://github.com/BerriAI/litellm/pull/19989)
|
||||
- Add support for configuring role_mappings via environment variables - [PR #19498](https://github.com/BerriAI/litellm/pull/19498)
|
||||
- Add Vertex AI LLM credentials sensitive keyword "vertex_credentials" for masking - [PR #19551](https://github.com/BerriAI/litellm/pull/19551)
|
||||
- Fix prevention of provider-prefixed model name leaks in responses - [PR #19943](https://github.com/BerriAI/litellm/pull/19943)
|
||||
- Fix proxy support for slashes in Google Vertex generateContent model names - [PR #19737](https://github.com/BerriAI/litellm/pull/19737), [PR #19753](https://github.com/BerriAI/litellm/pull/19753)
|
||||
- Support model names with slashes in Vertex AI passthrough URLs - [PR #19944](https://github.com/BerriAI/litellm/pull/19944)
|
||||
- Fix regression in Vertex AI passthroughs for router models - [PR #19967](https://github.com/BerriAI/litellm/pull/19967)
|
||||
- Add regression tests for Vertex AI passthrough model names - [PR #19855](https://github.com/BerriAI/litellm/pull/19855)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- **General**
|
||||
- Fix token calculations and refactor - [PR #19696](https://github.com/BerriAI/litellm/pull/19696)
|
||||
|
||||
## Management Endpoints / UI
|
||||
|
||||
#### Features
|
||||
|
||||
- **Proxy CLI Auth**
|
||||
- Add configurable CLI JWT expiration via environment variable - [PR #19780](https://github.com/BerriAI/litellm/pull/19780)
|
||||
- Fix team cli auth flow - [PR #19666](https://github.com/BerriAI/litellm/pull/19666)
|
||||
|
||||
- **Virtual Keys**
|
||||
- UI: Auto Truncation of Table Values - [PR #19718](https://github.com/BerriAI/litellm/pull/19718)
|
||||
- Fix Create Key: Expire Key Input Duration - [PR #19807](https://github.com/BerriAI/litellm/pull/19807)
|
||||
- Bulk Update Keys Endpoint - [PR #19886](https://github.com/BerriAI/litellm/pull/19886)
|
||||
|
||||
- **Logs View**
|
||||
- **v2 Logs view with side panel and improved UX** - [PR #20091](https://github.com/BerriAI/litellm/pull/20091)
|
||||
- New View to render "Tools" on Logs View - [PR #20093](https://github.com/BerriAI/litellm/pull/20093)
|
||||
- Add Pretty print view of request/response - [PR #20096](https://github.com/BerriAI/litellm/pull/20096)
|
||||
- Add error_message search in Spend Logs Endpoint - [PR #19960](https://github.com/BerriAI/litellm/pull/19960)
|
||||
- UI: Adding Error message search to ui spend logs - [PR #19963](https://github.com/BerriAI/litellm/pull/19963)
|
||||
- Spend Logs: Settings Modal - [PR #19918](https://github.com/BerriAI/litellm/pull/19918)
|
||||
- Fix error_code in Spend Logs metadata - [PR #20015](https://github.com/BerriAI/litellm/pull/20015)
|
||||
- Spend Logs: Show Current Store and Retention Status - [PR #20017](https://github.com/BerriAI/litellm/pull/20017)
|
||||
- Allow Dynamic Setting of store_prompts_in_spend_logs - [PR #19913](https://github.com/BerriAI/litellm/pull/19913)
|
||||
- [Docs: UI Spend Logs Settings](../../docs/proxy/ui_spend_log_settings) - [PR #20197](https://github.com/BerriAI/litellm/pull/20197)
|
||||
|
||||
- **Models + Endpoints**
|
||||
- Add sortBy and sortOrder params for /v2/model/info - [PR #19903](https://github.com/BerriAI/litellm/pull/19903)
|
||||
- Fix Sorting for /v2/model/info - [PR #19971](https://github.com/BerriAI/litellm/pull/19971)
|
||||
- UI: Model Page Server Sort - [PR #19908](https://github.com/BerriAI/litellm/pull/19908)
|
||||
|
||||
- **Usage & Analytics**
|
||||
- UI: Usage Export: Breakdown by Teams and Keys - [PR #19953](https://github.com/BerriAI/litellm/pull/19953)
|
||||
- UI: Usage: Model Breakdown Per Key - [PR #20039](https://github.com/BerriAI/litellm/pull/20039)
|
||||
|
||||
- **UI Improvements**
|
||||
- UI: Allow Admins to control what pages are visible on LeftNav - [PR #19907](https://github.com/BerriAI/litellm/pull/19907)
|
||||
- UI: Add Light/Dark Mode Switch for Development - [PR #19804](https://github.com/BerriAI/litellm/pull/19804)
|
||||
- UI: Dark Mode: Delete Resource Modal - [PR #20098](https://github.com/BerriAI/litellm/pull/20098)
|
||||
- UI: Tables: Reusable Table Sort Component - [PR #19970](https://github.com/BerriAI/litellm/pull/19970)
|
||||
- UI: New Badge Dot Render - [PR #20024](https://github.com/BerriAI/litellm/pull/20024)
|
||||
- UI: Feedback Prompts: Option To Hide Prompts - [PR #19831](https://github.com/BerriAI/litellm/pull/19831)
|
||||
- UI: Navbar: Fixed Default Logo + Bound Logo Box - [PR #20092](https://github.com/BerriAI/litellm/pull/20092)
|
||||
- UI: Navbar: User Dropdown - [PR #20095](https://github.com/BerriAI/litellm/pull/20095)
|
||||
- Change default key type from 'Default' to 'LLM API' - [PR #19516](https://github.com/BerriAI/litellm/pull/19516)
|
||||
|
||||
- **Team & User Management**
|
||||
- Fix /team/member_add User Email and ID Verifications - [PR #19814](https://github.com/BerriAI/litellm/pull/19814)
|
||||
- Fix SSO Email Case Sensitivity - [PR #19799](https://github.com/BerriAI/litellm/pull/19799)
|
||||
- UI: Internal User: Bulk Add - [PR #19721](https://github.com/BerriAI/litellm/pull/19721)
|
||||
|
||||
- **AI Gateway Features**
|
||||
- Add support for making silent LLM calls without logging - [PR #19544](https://github.com/BerriAI/litellm/pull/19544)
|
||||
- UI: Fix MCP tools instructions to display comma-separated strings - [PR #20101](https://github.com/BerriAI/litellm/pull/20101)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- Fix Model Name During Fallback - [PR #20177](https://github.com/BerriAI/litellm/pull/20177)
|
||||
- Fix Health Endpoints when Callback Objects Defined - [PR #20182](https://github.com/BerriAI/litellm/pull/20182)
|
||||
- Fix Unable to reset user max budget to unlimited - [PR #19796](https://github.com/BerriAI/litellm/pull/19796)
|
||||
- Fix Password comparison with non-ASCII characters - [PR #19568](https://github.com/BerriAI/litellm/pull/19568)
|
||||
- Correct error message for DISABLE_ADMIN_ENDPOINTS - [PR #19861](https://github.com/BerriAI/litellm/pull/19861)
|
||||
- Prevent clearing content filter patterns when editing guardrail - [PR #19671](https://github.com/BerriAI/litellm/pull/19671)
|
||||
- Fix Prompt Studio history to load tools and system messages - [PR #19920](https://github.com/BerriAI/litellm/pull/19920)
|
||||
- Add WATSONX_ZENAPIKEY to WatsonX credentials - [PR #20086](https://github.com/BerriAI/litellm/pull/20086)
|
||||
- UI: Vector Store: Allow Config Defined Models to Be Selected - [PR #20031](https://github.com/BerriAI/litellm/pull/20031)
|
||||
|
||||
## Logging / Guardrail / Prompt Management Integrations
|
||||
|
||||
#### Features
|
||||
|
||||
- **[DataDog](../../docs/proxy/logging#datadog)**
|
||||
- Add agent support for LLM Observability - [PR #19574](https://github.com/BerriAI/litellm/pull/19574)
|
||||
- Add datadog cost management support and fix startup callback issue - [PR #19584](https://github.com/BerriAI/litellm/pull/19584)
|
||||
- Add datadog_llm_observability to /health/services allowed list - [PR #19952](https://github.com/BerriAI/litellm/pull/19952)
|
||||
- Check for agent mode before requiring DD_API_KEY/DD_SITE - [PR #20156](https://github.com/BerriAI/litellm/pull/20156)
|
||||
|
||||
- **[OpenTelemetry](../../docs/observability/opentelemetry_integration)**
|
||||
- Propagate JWT auth metadata to OTEL spans - [PR #19627](https://github.com/BerriAI/litellm/pull/19627)
|
||||
- Fix thread leak in dynamic header path - [PR #19946](https://github.com/BerriAI/litellm/pull/19946)
|
||||
|
||||
- **[Prometheus](../../docs/proxy/logging#prometheus)**
|
||||
- Add callbacks and labels - [PR #19708](https://github.com/BerriAI/litellm/pull/19708)
|
||||
- Add clientip and user agent in metrics - [PR #19717](https://github.com/BerriAI/litellm/pull/19717)
|
||||
- Add tpm-rpm limit metrics - [PR #19725](https://github.com/BerriAI/litellm/pull/19725)
|
||||
- Add model_id label to metrics - [PR #19678](https://github.com/BerriAI/litellm/pull/19678)
|
||||
- Safely handle None metadata in logging - [PR #19691](https://github.com/BerriAI/litellm/pull/19691)
|
||||
- Resolve high CPU when router_settings in DB by avoiding REGISTRY.collect() - [PR #20087](https://github.com/BerriAI/litellm/pull/20087)
|
||||
|
||||
- **[Langfuse](../../docs/proxy/logging#langfuse)**
|
||||
- Add litellm_callback_logging_failures_metric for Langfuse, Langfuse Otel and other Otel providers - [PR #19636](https://github.com/BerriAI/litellm/pull/19636)
|
||||
|
||||
- **General Logging**
|
||||
- Use return value from CustomLogger.async_post_call_success_hook - [PR #19670](https://github.com/BerriAI/litellm/pull/19670)
|
||||
- Add async_post_call_response_headers_hook to CustomLogger - [PR #20083](https://github.com/BerriAI/litellm/pull/20083)
|
||||
- Add mock client factory pattern and mock support for PostHog, Helicone, and Braintrust integrations - [PR #19707](https://github.com/BerriAI/litellm/pull/19707)
|
||||
|
||||
#### Guardrails
|
||||
|
||||
- **[Presidio](../../docs/proxy/guardrails/pii_masking_v2)**
|
||||
- Reuse HTTP connections to prevent performance degradation - [PR #19964](https://github.com/BerriAI/litellm/pull/19964)
|
||||
|
||||
- **Onyx**
|
||||
- Add timeout to onyx guardrail - [PR #19731](https://github.com/BerriAI/litellm/pull/19731)
|
||||
|
||||
- **General**
|
||||
- Add guardrail model argument feature - [PR #19619](https://github.com/BerriAI/litellm/pull/19619)
|
||||
- Fix guardrails issues with streaming-response regex - [PR #19901](https://github.com/BerriAI/litellm/pull/19901)
|
||||
- Remove enterprise requirement for guardrail monitoring (docs) - [PR #19833](https://github.com/BerriAI/litellm/pull/19833)
|
||||
|
||||
## Spend Tracking, Budgets and Rate Limiting
|
||||
|
||||
- Add event-driven coordination for global spend query to prevent cache stampede - [PR #20030](https://github.com/BerriAI/litellm/pull/20030)
|
||||
|
||||
## Performance / Loadbalancing / Reliability improvements
|
||||
|
||||
- **Resolve high CPU when router_settings in DB** - by avoiding REGISTRY.collect() in PrometheusServicesLogger - [PR #20087](https://github.com/BerriAI/litellm/pull/20087)
|
||||
- **Reuse HTTP connections in Presidio** - to prevent performance degradation - [PR #19964](https://github.com/BerriAI/litellm/pull/19964)
|
||||
- **Event-driven coordination for global spend query** - prevent cache stampede - [PR #20030](https://github.com/BerriAI/litellm/pull/20030)
|
||||
- Fix recursive Pydantic validation issue - [PR #19531](https://github.com/BerriAI/litellm/pull/19531)
|
||||
- Refactor argument handling into helper function to reduce code bloat - [PR #19720](https://github.com/BerriAI/litellm/pull/19720)
|
||||
- Optimize logo fetching and resolve MCP import blockers - [PR #19719](https://github.com/BerriAI/litellm/pull/19719)
|
||||
- Improve logo download performance using async HTTP client - [PR #20155](https://github.com/BerriAI/litellm/pull/20155)
|
||||
- Fix server root path configuration - [PR #19790](https://github.com/BerriAI/litellm/pull/19790)
|
||||
- Refactor: Extract transport context creation into separate method - [PR #19794](https://github.com/BerriAI/litellm/pull/19794)
|
||||
- Add native_background_mode configuration to override polling_via_cache for specific models - [PR #19899](https://github.com/BerriAI/litellm/pull/19899)
|
||||
- Initialize tiktoken environment at import time to enable offline usage - [PR #19882](https://github.com/BerriAI/litellm/pull/19882)
|
||||
- Improve tiktoken performance using local cache in lazy loading - [PR #19774](https://github.com/BerriAI/litellm/pull/19774)
|
||||
- Fix timeout errors in chat completion calls to be correctly reported in failure callbacks - [PR #19842](https://github.com/BerriAI/litellm/pull/19842)
|
||||
- Fix environment variable type handling for NUM_RETRIES - [PR #19507](https://github.com/BerriAI/litellm/pull/19507)
|
||||
- Use safe_deep_copy in silent experiment kwargs to prevent mutation - [PR #20170](https://github.com/BerriAI/litellm/pull/20170)
|
||||
- Improve error handling by inspecting BadRequestError after all other policy types - [PR #19878](https://github.com/BerriAI/litellm/pull/19878)
|
||||
|
||||
## Database Changes
|
||||
|
||||
### Schema Updates
|
||||
|
||||
| Table | Change Type | Description | PR | Migration |
|
||||
| ----- | ----------- | ----------- | -- | --------- |
|
||||
| `LiteLLM_ManagedVectorStoresTable` | New Columns | Added `team_id` and `user_id` fields for permission management | [PR #19972](https://github.com/BerriAI/litellm/pull/19972) | [Migration](https://github.com/BerriAI/litellm/blob/main/litellm-proxy-extras/litellm_proxy_extras/migrations/20260131150814_add_team_user_to_vector_stores/migration.sql) |
|
||||
|
||||
### Migration Improvements
|
||||
|
||||
- Fix Docker: Use correct schema path for Prisma generation - [PR #19631](https://github.com/BerriAI/litellm/pull/19631)
|
||||
- Resolve 'relation does not exist' migration errors in setup_database - [PR #19281](https://github.com/BerriAI/litellm/pull/19281)
|
||||
- Fix migration issue and improve Docker image stability - [PR #19843](https://github.com/BerriAI/litellm/pull/19843)
|
||||
- Run Prisma generate as nobody user in non-root Docker container for security - [PR #20000](https://github.com/BerriAI/litellm/pull/20000)
|
||||
- Bump litellm-proxy-extras version to 0.4.28 - [PR #20166](https://github.com/BerriAI/litellm/pull/20166)
|
||||
|
||||
## Documentation Updates
|
||||
|
||||
- **[Add Claude Agents SDK x LiteLLM Guide](../../docs/mcp)** - [PR #20036](https://github.com/BerriAI/litellm/pull/20036)
|
||||
- **[Add Cookbook: Using Claude Agent SDK + MCPs with LiteLLM](https://github.com/BerriAI/litellm/tree/main/cookbook)** - [PR #20081](https://github.com/BerriAI/litellm/pull/20081)
|
||||
- Fix A2A Python SDK URL in documentation - [PR #19832](https://github.com/BerriAI/litellm/pull/19832)
|
||||
- **[Add Sarvam usage documentation](../../docs/providers/sarvam)** - [PR #19844](https://github.com/BerriAI/litellm/pull/19844)
|
||||
- **[Add supported input formats for embeddings](../../docs/embedding/supported_embedding)** - [PR #20073](https://github.com/BerriAI/litellm/pull/20073)
|
||||
- **[UI Spend Logs Settings Docs](../../docs/proxy/ui_spend_log_settings)** - [PR #20197](https://github.com/BerriAI/litellm/pull/20197)
|
||||
- Add OpenAI Agents SDK to OSS Adopters list in README - [PR #19820](https://github.com/BerriAI/litellm/pull/19820)
|
||||
- Update docs: Remove enterprise requirement for guardrail monitoring - [PR #19833](https://github.com/BerriAI/litellm/pull/19833)
|
||||
- Add missing environment variable documentation - [PR #20138](https://github.com/BerriAI/litellm/pull/20138)
|
||||
- Improve documentation blog index page - [PR #20188](https://github.com/BerriAI/litellm/pull/20188)
|
||||
|
||||
## Infrastructure / Testing Improvements
|
||||
|
||||
- Add test coverage for Router.get_valid_args and improve code coverage reporting - [PR #19797](https://github.com/BerriAI/litellm/pull/19797)
|
||||
- Add validation of model cost map as CI job - [PR #19993](https://github.com/BerriAI/litellm/pull/19993)
|
||||
- Add Realtime API benchmarks - [PR #20074](https://github.com/BerriAI/litellm/pull/20074)
|
||||
- Add Init Containers support in community helm chart - [PR #19816](https://github.com/BerriAI/litellm/pull/19816)
|
||||
- Add libsndfile to main Dockerfile for ARM64 audio processing support - [PR #19776](https://github.com/BerriAI/litellm/pull/19776)
|
||||
|
||||
## New Contributors
|
||||
|
||||
* @ruanjf made their first contribution in https://github.com/BerriAI/litellm/pull/19551
|
||||
* @moh-dev-stack made their first contribution in https://github.com/BerriAI/litellm/pull/19507
|
||||
* @formorter made their first contribution in https://github.com/BerriAI/litellm/pull/19498
|
||||
* @priyam-that made their first contribution in https://github.com/BerriAI/litellm/pull/19516
|
||||
* @marcosgriselli made their first contribution in https://github.com/BerriAI/litellm/pull/19550
|
||||
* @natimofeev made their first contribution in https://github.com/BerriAI/litellm/pull/19232
|
||||
* @zifeo made their first contribution in https://github.com/BerriAI/litellm/pull/19805
|
||||
* @pragyasardana made their first contribution in https://github.com/BerriAI/litellm/pull/19816
|
||||
* @ryewilson made their first contribution in https://github.com/BerriAI/litellm/pull/19833
|
||||
* @lizhen921 made their first contribution in https://github.com/BerriAI/litellm/pull/19919
|
||||
* @boarder7395 made their first contribution in https://github.com/BerriAI/litellm/pull/19666
|
||||
* @rushilchugh01 made their first contribution in https://github.com/BerriAI/litellm/pull/19938
|
||||
* @cfchase made their first contribution in https://github.com/BerriAI/litellm/pull/19893
|
||||
* @ayim made their first contribution in https://github.com/BerriAI/litellm/pull/19872
|
||||
* @varunsripad123 made their first contribution in https://github.com/BerriAI/litellm/pull/20018
|
||||
* @nht1206 made their first contribution in https://github.com/BerriAI/litellm/pull/20046
|
||||
* @genga6 made their first contribution in https://github.com/BerriAI/litellm/pull/20009
|
||||
|
||||
**Full Changelog**: https://github.com/BerriAI/litellm/compare/v1.81.3.rc...v1.81.6
|
||||
|
|
@ -79,6 +79,7 @@ const sidebars = {
|
|||
"proxy/guardrails/panw_prisma_airs",
|
||||
"proxy/guardrails/secret_detection",
|
||||
"proxy/guardrails/custom_guardrail",
|
||||
"proxy/guardrails/custom_code_guardrail",
|
||||
"proxy/guardrails/prompt_injection",
|
||||
"proxy/guardrails/tool_permission",
|
||||
"proxy/guardrails/zscaler_ai_guard",
|
||||
|
|
@ -128,6 +129,7 @@ const sidebars = {
|
|||
"tutorials/claude_mcp",
|
||||
"tutorials/claude_non_anthropic_models",
|
||||
"tutorials/claude_code_plugin_marketplace",
|
||||
"tutorials/claude_code_beta_headers",
|
||||
]
|
||||
},
|
||||
"tutorials/opencode_integration",
|
||||
|
|
@ -150,7 +152,9 @@ const sidebars = {
|
|||
},
|
||||
items: [
|
||||
"tutorials/claude_agent_sdk",
|
||||
"tutorials/copilotkit_sdk",
|
||||
"tutorials/google_adk",
|
||||
"tutorials/livekit_xai_realtime",
|
||||
]
|
||||
},
|
||||
|
||||
|
|
@ -442,6 +446,7 @@ const sidebars = {
|
|||
label: "Spend Tracking",
|
||||
items: [
|
||||
"proxy/cost_tracking",
|
||||
"proxy/request_tags",
|
||||
"proxy/custom_pricing",
|
||||
"proxy/pricing_calculator",
|
||||
"proxy/provider_margins",
|
||||
|
|
@ -468,6 +473,7 @@ const sidebars = {
|
|||
label: "/a2a - A2A Agent Gateway",
|
||||
items: [
|
||||
"a2a",
|
||||
"a2a_invoking_agents",
|
||||
"a2a_cost_tracking",
|
||||
"a2a_agent_permissions"
|
||||
],
|
||||
|
|
@ -537,6 +543,7 @@ const sidebars = {
|
|||
items: [
|
||||
"mcp",
|
||||
"mcp_usage",
|
||||
"mcp_semantic_filter",
|
||||
"mcp_control",
|
||||
"mcp_cost",
|
||||
"mcp_guardrail",
|
||||
|
|
@ -715,6 +722,7 @@ const sidebars = {
|
|||
"providers/bedrock_agents",
|
||||
"providers/bedrock_writer",
|
||||
"providers/bedrock_batches",
|
||||
"providers/bedrock_realtime_with_audio",
|
||||
"providers/aws_polly",
|
||||
"providers/bedrock_vector_store",
|
||||
]
|
||||
|
|
@ -847,7 +855,14 @@ const sidebars = {
|
|||
"providers/watsonx/audio_transcription",
|
||||
]
|
||||
},
|
||||
"providers/xai",
|
||||
{
|
||||
type: "category",
|
||||
label: "xAI",
|
||||
items: [
|
||||
"providers/xai",
|
||||
"providers/xai_realtime",
|
||||
]
|
||||
},
|
||||
"providers/xiaomi_mimo",
|
||||
"providers/xinference",
|
||||
"providers/zai",
|
||||
|
|
@ -1041,6 +1056,7 @@ const sidebars = {
|
|||
type: "category",
|
||||
label: "Issue Reporting",
|
||||
items: [
|
||||
"troubleshoot/prisma_migrations",
|
||||
"troubleshoot/cpu_issues",
|
||||
"troubleshoot/memory_issues",
|
||||
"troubleshoot/spend_queue_warnings",
|
||||
|
|
|
|||
BIN
enterprise/dist/litellm_enterprise-0.1.29-py3-none-any.whl
vendored
Normal file
BIN
enterprise/dist/litellm_enterprise-0.1.29-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
enterprise/dist/litellm_enterprise-0.1.29.tar.gz
vendored
Normal file
BIN
enterprise/dist/litellm_enterprise-0.1.29.tar.gz
vendored
Normal file
Binary file not shown.
BIN
enterprise/dist/litellm_enterprise-0.1.30-py3-none-any.whl
vendored
Normal file
BIN
enterprise/dist/litellm_enterprise-0.1.30-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
enterprise/dist/litellm_enterprise-0.1.30.tar.gz
vendored
Normal file
BIN
enterprise/dist/litellm_enterprise-0.1.30.tar.gz
vendored
Normal file
Binary file not shown.
BIN
enterprise/dist/litellm_enterprise-0.1.31-py3-none-any.whl
vendored
Normal file
BIN
enterprise/dist/litellm_enterprise-0.1.31-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
enterprise/dist/litellm_enterprise-0.1.31.tar.gz
vendored
Normal file
BIN
enterprise/dist/litellm_enterprise-0.1.31.tar.gz
vendored
Normal file
Binary file not shown.
|
|
@ -30,8 +30,15 @@ from litellm.integrations.email_templates.user_invitation_email import (
|
|||
from litellm.integrations.email_templates.templates import (
|
||||
MAX_BUDGET_ALERT_EMAIL_TEMPLATE,
|
||||
SOFT_BUDGET_ALERT_EMAIL_TEMPLATE,
|
||||
TEAM_SOFT_BUDGET_ALERT_EMAIL_TEMPLATE,
|
||||
)
|
||||
from litellm.proxy._types import (
|
||||
CallInfo,
|
||||
InvitationNew,
|
||||
Litellm_EntityType,
|
||||
UserAPIKeyAuth,
|
||||
WebhookEvent,
|
||||
)
|
||||
from litellm.proxy._types import CallInfo, InvitationNew, UserAPIKeyAuth, WebhookEvent
|
||||
from litellm.secret_managers.main import get_secret_bool
|
||||
from litellm.types.integrations.slack_alerting import LITELLM_LOGO_URL
|
||||
from litellm.constants import (
|
||||
|
|
@ -217,6 +224,78 @@ class BaseEmailLogger(CustomLogger):
|
|||
)
|
||||
pass
|
||||
|
||||
async def send_team_soft_budget_alert_email(self, event: WebhookEvent):
|
||||
"""
|
||||
Send email to team members when team soft budget is crossed
|
||||
Supports multiple recipients via alert_emails field from team metadata
|
||||
"""
|
||||
# Collect all recipient emails
|
||||
recipient_emails: List[str] = []
|
||||
|
||||
# Add additional alert emails from team metadata.soft_budget_alert_emails
|
||||
if hasattr(event, "alert_emails") and event.alert_emails:
|
||||
for email in event.alert_emails:
|
||||
if email and email not in recipient_emails: # Avoid duplicates
|
||||
recipient_emails.append(email)
|
||||
|
||||
# If no recipients found, skip sending
|
||||
if not recipient_emails:
|
||||
verbose_proxy_logger.warning(
|
||||
f"No recipient emails found for team soft budget alert. event={event.model_dump(exclude_none=True)}"
|
||||
)
|
||||
return
|
||||
|
||||
# Validate that we have at least one valid email address
|
||||
first_recipient_email = recipient_emails[0]
|
||||
if not first_recipient_email or not first_recipient_email.strip():
|
||||
verbose_proxy_logger.warning(
|
||||
f"Invalid recipient email found for team soft budget alert. event={event.model_dump(exclude_none=True)}"
|
||||
)
|
||||
return
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
f"send_team_soft_budget_alert_email_event: {json.dumps(event.model_dump(exclude_none=True), indent=4, default=str)}"
|
||||
)
|
||||
|
||||
# Get email params using the first recipient email (for template formatting)
|
||||
# For team alerts with alert_emails, we don't need user_id lookup since we already have email addresses
|
||||
# Pass user_id=None to prevent _get_email_params from trying to look up email from a potentially None user_id
|
||||
email_params = await self._get_email_params(
|
||||
email_event=EmailEvent.soft_budget_crossed,
|
||||
user_id=None, # Team alerts don't require user_id when alert_emails are provided
|
||||
user_email=first_recipient_email,
|
||||
event_message=event.event_message,
|
||||
)
|
||||
|
||||
# Format budget values
|
||||
soft_budget_str = f"${event.soft_budget}" if event.soft_budget is not None else "N/A"
|
||||
spend_str = f"${event.spend}" if event.spend is not None else "$0.00"
|
||||
max_budget_info = ""
|
||||
if event.max_budget is not None:
|
||||
max_budget_info = f"<b>Maximum Budget:</b> ${event.max_budget} <br />"
|
||||
|
||||
# Use team alias or generic greeting
|
||||
team_alias = event.team_alias or "Team"
|
||||
|
||||
email_html_content = TEAM_SOFT_BUDGET_ALERT_EMAIL_TEMPLATE.format(
|
||||
email_logo_url=email_params.logo_url,
|
||||
team_alias=team_alias,
|
||||
soft_budget=soft_budget_str,
|
||||
spend=spend_str,
|
||||
max_budget_info=max_budget_info,
|
||||
base_url=email_params.base_url,
|
||||
email_support_contact=email_params.support_contact,
|
||||
)
|
||||
|
||||
# Send email to all recipients
|
||||
await self.send_email(
|
||||
from_email=self.DEFAULT_LITELLM_EMAIL,
|
||||
to_email=recipient_emails,
|
||||
subject=email_params.subject,
|
||||
html_body=email_html_content,
|
||||
)
|
||||
pass
|
||||
|
||||
async def send_max_budget_alert_email(self, event: WebhookEvent):
|
||||
"""
|
||||
Send email to user when max budget alert threshold is reached
|
||||
|
|
@ -285,15 +364,36 @@ class BaseEmailLogger(CustomLogger):
|
|||
# - Don't re-alert, if alert already sent
|
||||
_cache: DualCache = self.internal_usage_cache
|
||||
|
||||
# percent of max_budget left to spend
|
||||
if user_info.max_budget is None and user_info.soft_budget is None:
|
||||
return
|
||||
|
||||
# For soft_budget alerts, check if we've already sent an alert
|
||||
if type == "soft_budget":
|
||||
# For team soft budget alerts, we only need team soft_budget to be set
|
||||
# For other entity types, we need either max_budget or soft_budget
|
||||
if user_info.event_group == Litellm_EntityType.TEAM:
|
||||
if user_info.soft_budget is None:
|
||||
return
|
||||
# For team soft budget alerts, require alert_emails to be configured
|
||||
# Team soft budget alerts are sent via metadata.soft_budget_alerting_emails
|
||||
if user_info.alert_emails is None or len(user_info.alert_emails) == 0:
|
||||
verbose_proxy_logger.debug(
|
||||
"Skipping team soft budget email alert: no alert_emails configured",
|
||||
)
|
||||
return
|
||||
else:
|
||||
# For non-team alerts, require either max_budget or soft_budget
|
||||
if user_info.max_budget is None and user_info.soft_budget is None:
|
||||
return
|
||||
if user_info.soft_budget is not None and user_info.spend >= user_info.soft_budget:
|
||||
# Generate cache key based on event type and identifier
|
||||
_id = user_info.token or user_info.user_id or "default_id"
|
||||
# Use appropriate ID based on event_group to ensure unique cache keys per entity type
|
||||
if user_info.event_group == Litellm_EntityType.TEAM:
|
||||
_id = user_info.team_id or "default_id"
|
||||
elif user_info.event_group == Litellm_EntityType.ORGANIZATION:
|
||||
_id = user_info.organization_id or "default_id"
|
||||
elif user_info.event_group == Litellm_EntityType.USER:
|
||||
_id = user_info.user_id or "default_id"
|
||||
else:
|
||||
# For KEY and other types, use token or user_id
|
||||
_id = user_info.token or user_info.user_id or "default_id"
|
||||
_cache_key = f"email_budget_alerts:soft_budget_crossed:{_id}"
|
||||
|
||||
# Check if we've already sent this alert
|
||||
|
|
@ -318,10 +418,15 @@ class BaseEmailLogger(CustomLogger):
|
|||
projected_exceeded_date=user_info.projected_exceeded_date,
|
||||
projected_spend=user_info.projected_spend,
|
||||
event_group=user_info.event_group,
|
||||
alert_emails=user_info.alert_emails,
|
||||
)
|
||||
|
||||
try:
|
||||
await self.send_soft_budget_alert_email(webhook_event)
|
||||
# Use team-specific function for team alerts, otherwise use standard function
|
||||
if user_info.event_group == Litellm_EntityType.TEAM:
|
||||
await self.send_team_soft_budget_alert_email(webhook_event)
|
||||
else:
|
||||
await self.send_soft_budget_alert_email(webhook_event)
|
||||
|
||||
# Cache the alert to prevent duplicate sends
|
||||
await _cache.async_set_cache(
|
||||
|
|
|
|||
|
|
@ -53,7 +53,7 @@ class CheckBatchCost:
|
|||
|
||||
jobs = await self.prisma_client.db.litellm_managedobjecttable.find_many(
|
||||
where={
|
||||
"status": "validating",
|
||||
"status": {"in": ["validating", "in_progress", "finalizing"]},
|
||||
"file_purpose": "batch",
|
||||
}
|
||||
)
|
||||
|
|
|
|||
|
|
@ -166,7 +166,11 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
"updated_by": user_api_key_dict.user_id,
|
||||
"status": file_object.status,
|
||||
},
|
||||
"update": {}, # don't do anything if it already exists
|
||||
"update": {
|
||||
"file_object": file_object.model_dump_json(),
|
||||
"status": file_object.status,
|
||||
"updated_by": user_api_key_dict.user_id,
|
||||
}, # FIX: Update status and file_object on every operation to keep state in sync
|
||||
},
|
||||
)
|
||||
|
||||
|
|
@ -354,6 +358,31 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
)
|
||||
return False
|
||||
|
||||
async def check_file_ids_access(
|
||||
self, file_ids: List[str], user_api_key_dict: UserAPIKeyAuth
|
||||
) -> None:
|
||||
"""
|
||||
Check if the user has access to a list of file IDs.
|
||||
Only checks managed (unified) file IDs.
|
||||
|
||||
Args:
|
||||
file_ids: List of file IDs to check access for
|
||||
user_api_key_dict: User API key authentication details
|
||||
|
||||
Raises:
|
||||
HTTPException: If user doesn't have access to any of the files
|
||||
"""
|
||||
for file_id in file_ids:
|
||||
is_unified_file_id = _is_base64_encoded_unified_file_id(file_id)
|
||||
if is_unified_file_id:
|
||||
if not await self.can_user_call_unified_file_id(
|
||||
file_id, user_api_key_dict
|
||||
):
|
||||
raise HTTPException(
|
||||
status_code=403,
|
||||
detail=f"User {user_api_key_dict.user_id} does not have access to the file {file_id}",
|
||||
)
|
||||
|
||||
async def async_pre_call_hook( # noqa: PLR0915
|
||||
self,
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
|
|
@ -387,6 +416,9 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
if messages:
|
||||
file_ids = self.get_file_ids_from_messages(messages)
|
||||
if file_ids:
|
||||
# Check user has access to all managed files
|
||||
await self.check_file_ids_access(file_ids, user_api_key_dict)
|
||||
|
||||
# Check if any files are stored in storage backends and need base64 conversion
|
||||
# This is needed for Vertex AI/Gemini which requires base64 content
|
||||
is_vertex_ai = model and ("vertex_ai" in model or "gemini" in model.lower())
|
||||
|
|
@ -402,15 +434,27 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
)
|
||||
data["model_file_id_mapping"] = model_file_id_mapping
|
||||
elif call_type == CallTypes.aresponses.value or call_type == CallTypes.responses.value:
|
||||
# Handle managed files in responses API input
|
||||
# Handle managed files in responses API input and tools
|
||||
file_ids = []
|
||||
|
||||
# Extract file IDs from input parameter
|
||||
input_data = data.get("input")
|
||||
if input_data:
|
||||
file_ids = self.get_file_ids_from_responses_input(input_data)
|
||||
if file_ids:
|
||||
model_file_id_mapping = await self.get_model_file_id_mapping(
|
||||
file_ids, user_api_key_dict.parent_otel_span
|
||||
)
|
||||
data["model_file_id_mapping"] = model_file_id_mapping
|
||||
file_ids.extend(self.get_file_ids_from_responses_input(input_data))
|
||||
|
||||
# Extract file IDs from tools parameter (e.g., code_interpreter container)
|
||||
tools = data.get("tools")
|
||||
if tools:
|
||||
file_ids.extend(self.get_file_ids_from_responses_tools(tools))
|
||||
|
||||
if file_ids:
|
||||
# Check user has access to all managed files
|
||||
await self.check_file_ids_access(file_ids, user_api_key_dict)
|
||||
|
||||
model_file_id_mapping = await self.get_model_file_id_mapping(
|
||||
file_ids, user_api_key_dict.parent_otel_span
|
||||
)
|
||||
data["model_file_id_mapping"] = model_file_id_mapping
|
||||
elif call_type == CallTypes.afile_content.value:
|
||||
retrieve_file_id = cast(Optional[str], data.get("file_id"))
|
||||
potential_file_id = (
|
||||
|
|
@ -460,8 +504,6 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
if retrieve_object_id
|
||||
else False
|
||||
)
|
||||
print(f"🔥potential_llm_object_id: {potential_llm_object_id}")
|
||||
print(f"🔥retrieve_object_id: {retrieve_object_id}")
|
||||
if potential_llm_object_id and retrieve_object_id:
|
||||
## VALIDATE USER HAS ACCESS TO THE OBJECT ##
|
||||
if not await self.can_user_call_unified_object_id(
|
||||
|
|
@ -614,6 +656,41 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
|
||||
return file_ids
|
||||
|
||||
def get_file_ids_from_responses_tools(
|
||||
self, tools: List[Dict[str, Any]]
|
||||
) -> List[str]:
|
||||
"""
|
||||
Gets file ids from responses API tools parameter.
|
||||
|
||||
The tools can contain code_interpreter with container.file_ids:
|
||||
[
|
||||
{
|
||||
"type": "code_interpreter",
|
||||
"container": {"type": "auto", "file_ids": ["file-123", "file-456"]}
|
||||
}
|
||||
]
|
||||
"""
|
||||
file_ids: List[str] = []
|
||||
|
||||
if not isinstance(tools, list):
|
||||
return file_ids
|
||||
|
||||
for tool in tools:
|
||||
if not isinstance(tool, dict):
|
||||
continue
|
||||
|
||||
# Check for code_interpreter with container file_ids
|
||||
if tool.get("type") == "code_interpreter":
|
||||
container = tool.get("container")
|
||||
if isinstance(container, dict):
|
||||
container_file_ids = container.get("file_ids")
|
||||
if isinstance(container_file_ids, list):
|
||||
for file_id in container_file_ids:
|
||||
if isinstance(file_id, str):
|
||||
file_ids.append(file_id)
|
||||
|
||||
return file_ids
|
||||
|
||||
async def get_model_file_id_mapping(
|
||||
self, file_ids: List[str], litellm_parent_otel_span: Span
|
||||
) -> dict:
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "litellm-enterprise"
|
||||
version = "0.1.28"
|
||||
version = "0.1.31"
|
||||
description = "Package for LiteLLM Enterprise features"
|
||||
authors = ["BerriAI"]
|
||||
readme = "README.md"
|
||||
|
|
@ -22,7 +22,7 @@ requires = ["poetry-core"]
|
|||
build-backend = "poetry.core.masonry.api"
|
||||
|
||||
[tool.commitizen]
|
||||
version = "0.1.28"
|
||||
version = "0.1.31"
|
||||
version_files = [
|
||||
"pyproject.toml:version",
|
||||
"../requirements.txt:litellm-enterprise==",
|
||||
|
|
|
|||
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.30-py3-none-any.whl
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.30-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.30.tar.gz
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.30.tar.gz
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.31-py3-none-any.whl
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.31-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.31.tar.gz
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.31.tar.gz
vendored
Normal file
Binary file not shown.
|
|
@ -0,0 +1,6 @@
|
|||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_DeletedTeamTable" ADD COLUMN "allow_team_guardrail_config" BOOLEAN NOT NULL DEFAULT false;
|
||||
|
||||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_TeamTable" ADD COLUMN "allow_team_guardrail_config" BOOLEAN NOT NULL DEFAULT false;
|
||||
|
||||
|
|
@ -0,0 +1,3 @@
|
|||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_TeamTable" ADD COLUMN "soft_budget" DOUBLE PRECISION;
|
||||
|
||||
|
|
@ -113,6 +113,7 @@ model LiteLLM_TeamTable {
|
|||
members_with_roles Json @default("{}")
|
||||
metadata Json @default("{}")
|
||||
max_budget Float?
|
||||
soft_budget Float?
|
||||
spend Float @default(0.0)
|
||||
models String[]
|
||||
max_parallel_requests Int?
|
||||
|
|
@ -129,6 +130,7 @@ model LiteLLM_TeamTable {
|
|||
team_member_permissions String[] @default([])
|
||||
policies String[] @default([])
|
||||
model_id Int? @unique // id for LiteLLM_ModelTable -> stores team-level model aliases
|
||||
allow_team_guardrail_config Boolean @default(false) // if true, team admin can configure guardrails for this team
|
||||
litellm_organization_table LiteLLM_OrganizationTable? @relation(fields: [organization_id], references: [organization_id])
|
||||
litellm_model_table LiteLLM_ModelTable? @relation(fields: [model_id], references: [id])
|
||||
object_permission LiteLLM_ObjectPermissionTable? @relation(fields: [object_permission_id], references: [object_permission_id])
|
||||
|
|
@ -160,7 +162,8 @@ model LiteLLM_DeletedTeamTable {
|
|||
team_member_permissions String[] @default([])
|
||||
policies String[] @default([])
|
||||
model_id Int? // id for LiteLLM_ModelTable -> stores team-level model aliases
|
||||
|
||||
allow_team_guardrail_config Boolean @default(false)
|
||||
|
||||
// Original timestamps from team creation/updates
|
||||
created_at DateTime? @map("created_at")
|
||||
updated_at DateTime? @map("updated_at")
|
||||
|
|
@ -774,6 +777,7 @@ model LiteLLM_GuardrailsTable {
|
|||
guardrail_name String @unique
|
||||
litellm_params Json
|
||||
guardrail_info Json?
|
||||
team_id String?
|
||||
created_at DateTime @default(now())
|
||||
updated_at DateTime @updatedAt
|
||||
}
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "litellm-proxy-extras"
|
||||
version = "0.4.29"
|
||||
version = "0.4.31"
|
||||
description = "Additional files for the LiteLLM Proxy. Reduces the size of the main litellm package."
|
||||
authors = ["BerriAI"]
|
||||
readme = "README.md"
|
||||
|
|
@ -22,7 +22,7 @@ requires = ["poetry-core"]
|
|||
build-backend = "poetry.core.masonry.api"
|
||||
|
||||
[tool.commitizen]
|
||||
version = "0.4.29"
|
||||
version = "0.4.31"
|
||||
version_files = [
|
||||
"pyproject.toml:version",
|
||||
"../requirements.txt:litellm-proxy-extras==",
|
||||
|
|
|
|||
|
|
@ -261,6 +261,8 @@ extra_spend_tag_headers: Optional[List[str]] = None
|
|||
in_memory_llm_clients_cache: "LLMClientCache"
|
||||
safe_memory_mode: bool = False
|
||||
enable_azure_ad_token_refresh: Optional[bool] = False
|
||||
# Proxy Authentication - auto-obtain/refresh OAuth2/JWT tokens for LiteLLM Proxy
|
||||
proxy_auth: Optional[Any] = None
|
||||
### DEFAULT AZURE API VERSION ###
|
||||
AZURE_DEFAULT_API_VERSION = "2025-02-01-preview" # this is updated to the latest
|
||||
### DEFAULT WATSONX API VERSION ###
|
||||
|
|
@ -351,7 +353,7 @@ default_team_settings: Optional[List] = None
|
|||
max_user_budget: Optional[float] = None
|
||||
default_max_internal_user_budget: Optional[float] = None
|
||||
max_internal_user_budget: Optional[float] = None
|
||||
max_ui_session_budget: Optional[float] = 10 # $10 USD budgets for UI Chat sessions
|
||||
max_ui_session_budget: Optional[float] = 0.25 # $0.25 USD budgets for UI Chat sessions
|
||||
internal_user_budget_duration: Optional[str] = None
|
||||
tag_budget_config: Optional[Dict[str, "BudgetConfig"]] = None
|
||||
max_end_user_budget: Optional[float] = None
|
||||
|
|
@ -1378,6 +1380,7 @@ if TYPE_CHECKING:
|
|||
from .llms.topaz.image_variations.transformation import TopazImageVariationConfig as TopazImageVariationConfig
|
||||
from litellm.llms.openai.completion.transformation import OpenAITextCompletionConfig as OpenAITextCompletionConfig
|
||||
from .llms.groq.chat.transformation import GroqChatConfig as GroqChatConfig
|
||||
from .llms.a2a.chat.transformation import A2AConfig as A2AConfig
|
||||
from .llms.voyage.embedding.transformation import VoyageEmbeddingConfig as VoyageEmbeddingConfig
|
||||
from .llms.voyage.embedding.transformation_contextual import VoyageContextualEmbeddingConfig as VoyageContextualEmbeddingConfig
|
||||
from .llms.infinity.embedding.transformation import InfinityEmbeddingConfig as InfinityEmbeddingConfig
|
||||
|
|
|
|||
|
|
@ -213,6 +213,7 @@ LLM_CONFIG_NAMES = (
|
|||
"TopazImageVariationConfig",
|
||||
"OpenAITextCompletionConfig",
|
||||
"GroqChatConfig",
|
||||
"A2AConfig",
|
||||
"GenAIHubOrchestrationConfig",
|
||||
"VoyageEmbeddingConfig",
|
||||
"VoyageContextualEmbeddingConfig",
|
||||
|
|
@ -850,6 +851,7 @@ _LLM_CONFIGS_IMPORT_MAP = {
|
|||
"OpenAITextCompletionConfig",
|
||||
),
|
||||
"GroqChatConfig": (".llms.groq.chat.transformation", "GroqChatConfig"),
|
||||
"A2AConfig": (".llms.a2a.chat.transformation", "A2AConfig"),
|
||||
"GenAIHubOrchestrationConfig": (
|
||||
".llms.sap.chat.transformation",
|
||||
"GenAIHubOrchestrationConfig",
|
||||
|
|
|
|||
30
litellm/anthropic_beta_headers_config.json
Normal file
30
litellm/anthropic_beta_headers_config.json
Normal file
|
|
@ -0,0 +1,30 @@
|
|||
{
|
||||
"description": "Unsupported Anthropic beta headers for each provider. Headers listed here will be dropped. Headers not listed are passed through as-is.",
|
||||
"anthropic": [],
|
||||
"azure_ai": [],
|
||||
"bedrock_converse": [
|
||||
"prompt-caching-scope-2026-01-05",
|
||||
"bash_20250124",
|
||||
"bash_20241022",
|
||||
"text_editor_20250124",
|
||||
"text_editor_20241022",
|
||||
"compact-2026-01-12",
|
||||
"advanced-tool-use-2025-11-20",
|
||||
"web-fetch-2025-09-10",
|
||||
"code-execution-2025-08-25",
|
||||
"skills-2025-10-02",
|
||||
"files-api-2025-04-14"
|
||||
],
|
||||
"bedrock": [
|
||||
"advanced-tool-use-2025-11-20",
|
||||
"prompt-caching-scope-2026-01-05",
|
||||
"structured-outputs-2025-11-13",
|
||||
"web-fetch-2025-09-10",
|
||||
"code-execution-2025-08-25",
|
||||
"skills-2025-10-02",
|
||||
"files-api-2025-04-14"
|
||||
],
|
||||
"vertex_ai": [
|
||||
"prompt-caching-scope-2026-01-05"
|
||||
]
|
||||
}
|
||||
221
litellm/anthropic_beta_headers_manager.py
Normal file
221
litellm/anthropic_beta_headers_manager.py
Normal file
|
|
@ -0,0 +1,221 @@
|
|||
"""
|
||||
Centralized manager for Anthropic beta headers across different providers.
|
||||
|
||||
This module provides utilities to:
|
||||
1. Load beta header configuration from JSON (lists unsupported headers per provider)
|
||||
2. Filter out unsupported beta headers
|
||||
3. Handle provider-specific header name mappings (e.g., advanced-tool-use -> tool-search-tool)
|
||||
|
||||
Design:
|
||||
- JSON config lists UNSUPPORTED headers for each provider
|
||||
- Headers not in the unsupported list are passed through
|
||||
- Header mappings allow renaming headers for specific providers
|
||||
"""
|
||||
|
||||
import json
|
||||
import os
|
||||
from typing import Dict, List, Optional, Set
|
||||
|
||||
from litellm.litellm_core_utils.litellm_logging import verbose_logger
|
||||
|
||||
# Cache for the loaded configuration
|
||||
_BETA_HEADERS_CONFIG: Optional[Dict] = None
|
||||
|
||||
|
||||
def _load_beta_headers_config() -> Dict:
|
||||
"""
|
||||
Load the beta headers configuration from JSON file.
|
||||
Uses caching to avoid repeated file reads.
|
||||
|
||||
Returns:
|
||||
Dict containing the beta headers configuration
|
||||
"""
|
||||
global _BETA_HEADERS_CONFIG
|
||||
|
||||
if _BETA_HEADERS_CONFIG is not None:
|
||||
return _BETA_HEADERS_CONFIG
|
||||
|
||||
config_path = os.path.join(
|
||||
os.path.dirname(__file__),
|
||||
"anthropic_beta_headers_config.json"
|
||||
)
|
||||
|
||||
try:
|
||||
with open(config_path, "r") as f:
|
||||
_BETA_HEADERS_CONFIG = json.load(f)
|
||||
verbose_logger.debug(f"Loaded beta headers config from {config_path}")
|
||||
return _BETA_HEADERS_CONFIG
|
||||
except Exception as e:
|
||||
verbose_logger.error(f"Failed to load beta headers config: {e}")
|
||||
# Return empty config as fallback
|
||||
return {
|
||||
"anthropic": [],
|
||||
"azure_ai": [],
|
||||
"bedrock": [],
|
||||
"bedrock_converse": [],
|
||||
"vertex_ai": []
|
||||
}
|
||||
|
||||
|
||||
def get_provider_name(provider: str) -> str:
|
||||
"""
|
||||
Resolve provider aliases to canonical provider names.
|
||||
|
||||
Args:
|
||||
provider: Provider name (may be an alias)
|
||||
|
||||
Returns:
|
||||
Canonical provider name
|
||||
"""
|
||||
config = _load_beta_headers_config()
|
||||
aliases = config.get("provider_aliases", {})
|
||||
return aliases.get(provider, provider)
|
||||
|
||||
|
||||
def filter_and_transform_beta_headers(
|
||||
beta_headers: List[str],
|
||||
provider: str,
|
||||
) -> List[str]:
|
||||
"""
|
||||
Filter beta headers based on provider's unsupported list.
|
||||
|
||||
This function:
|
||||
1. Removes headers that are in the provider's unsupported list
|
||||
2. Passes through all other headers as-is
|
||||
|
||||
Note: Header transformations/mappings (e.g., advanced-tool-use -> tool-search-tool)
|
||||
are handled in each provider's transformation code, not here.
|
||||
|
||||
Args:
|
||||
beta_headers: List of Anthropic beta header values
|
||||
provider: Provider name (e.g., "anthropic", "bedrock", "vertex_ai")
|
||||
|
||||
Returns:
|
||||
List of filtered beta headers for the provider
|
||||
"""
|
||||
if not beta_headers:
|
||||
return []
|
||||
|
||||
config = _load_beta_headers_config()
|
||||
provider = get_provider_name(provider)
|
||||
|
||||
# Get unsupported headers for this provider
|
||||
unsupported_headers = set(config.get(provider, []))
|
||||
|
||||
filtered_headers: Set[str] = set()
|
||||
|
||||
for header in beta_headers:
|
||||
header = header.strip()
|
||||
|
||||
# Skip if header is unsupported
|
||||
if header in unsupported_headers:
|
||||
verbose_logger.debug(
|
||||
f"Dropping unsupported beta header '{header}' for provider '{provider}'"
|
||||
)
|
||||
continue
|
||||
|
||||
# Pass through as-is
|
||||
filtered_headers.add(header)
|
||||
|
||||
return sorted(list(filtered_headers))
|
||||
|
||||
|
||||
def is_beta_header_supported(
|
||||
beta_header: str,
|
||||
provider: str,
|
||||
) -> bool:
|
||||
"""
|
||||
Check if a specific beta header is supported by a provider.
|
||||
|
||||
Args:
|
||||
beta_header: The Anthropic beta header value
|
||||
provider: Provider name
|
||||
|
||||
Returns:
|
||||
True if the header is supported (not in unsupported list), False otherwise
|
||||
"""
|
||||
config = _load_beta_headers_config()
|
||||
provider = get_provider_name(provider)
|
||||
unsupported_headers = set(config.get(provider, []))
|
||||
return beta_header not in unsupported_headers
|
||||
|
||||
|
||||
def get_provider_beta_header(
|
||||
anthropic_beta_header: str,
|
||||
provider: str,
|
||||
) -> Optional[str]:
|
||||
"""
|
||||
Check if a beta header is supported by a provider.
|
||||
|
||||
Note: This does NOT handle header transformations/mappings.
|
||||
Those are handled in each provider's transformation code.
|
||||
|
||||
Args:
|
||||
anthropic_beta_header: The Anthropic beta header value
|
||||
provider: Provider name
|
||||
|
||||
Returns:
|
||||
The original header if supported, or None if unsupported
|
||||
"""
|
||||
config = _load_beta_headers_config()
|
||||
provider = get_provider_name(provider)
|
||||
|
||||
# Check if unsupported
|
||||
unsupported_headers = set(config.get(provider, []))
|
||||
if anthropic_beta_header in unsupported_headers:
|
||||
return None
|
||||
|
||||
return anthropic_beta_header
|
||||
|
||||
|
||||
def update_headers_with_filtered_beta(
|
||||
headers: dict,
|
||||
provider: str,
|
||||
) -> dict:
|
||||
"""
|
||||
Update headers dict by filtering and transforming anthropic-beta header values.
|
||||
Modifies the headers dict in place and returns it.
|
||||
|
||||
Args:
|
||||
headers: Request headers dict (will be modified in place)
|
||||
provider: Provider name
|
||||
|
||||
Returns:
|
||||
Updated headers dict
|
||||
"""
|
||||
existing_beta = headers.get("anthropic-beta")
|
||||
if not existing_beta:
|
||||
return headers
|
||||
|
||||
# Parse existing beta headers
|
||||
beta_values = [b.strip() for b in existing_beta.split(",") if b.strip()]
|
||||
|
||||
# Filter and transform based on provider
|
||||
filtered_beta_values = filter_and_transform_beta_headers(
|
||||
beta_headers=beta_values,
|
||||
provider=provider,
|
||||
)
|
||||
|
||||
# Update or remove the header
|
||||
if filtered_beta_values:
|
||||
headers["anthropic-beta"] = ",".join(filtered_beta_values)
|
||||
else:
|
||||
# Remove the header if no values remain
|
||||
headers.pop("anthropic-beta", None)
|
||||
|
||||
return headers
|
||||
|
||||
|
||||
def get_unsupported_headers(provider: str) -> List[str]:
|
||||
"""
|
||||
Get all beta headers that are unsupported by a provider.
|
||||
|
||||
Args:
|
||||
provider: Provider name
|
||||
|
||||
Returns:
|
||||
List of unsupported Anthropic beta header names
|
||||
"""
|
||||
config = _load_beta_headers_config()
|
||||
provider = get_provider_name(provider)
|
||||
return config.get(provider, [])
|
||||
|
|
@ -329,6 +329,9 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
else:
|
||||
request_data[key] = value
|
||||
|
||||
if headers:
|
||||
request_data["extra_headers"] = headers
|
||||
|
||||
return request_data
|
||||
|
||||
@staticmethod
|
||||
|
|
|
|||
|
|
@ -67,6 +67,25 @@ DEFAULT_REASONING_EFFORT_DISABLE_THINKING_BUDGET = int(
|
|||
os.getenv("DEFAULT_REASONING_EFFORT_DISABLE_THINKING_BUDGET", 0)
|
||||
)
|
||||
|
||||
# MCP Semantic Tool Filter Defaults
|
||||
DEFAULT_MCP_SEMANTIC_FILTER_EMBEDDING_MODEL = str(
|
||||
os.getenv("DEFAULT_MCP_SEMANTIC_FILTER_EMBEDDING_MODEL", "text-embedding-3-small")
|
||||
)
|
||||
DEFAULT_MCP_SEMANTIC_FILTER_TOP_K = int(
|
||||
os.getenv("DEFAULT_MCP_SEMANTIC_FILTER_TOP_K", 10)
|
||||
)
|
||||
DEFAULT_MCP_SEMANTIC_FILTER_SIMILARITY_THRESHOLD = float(
|
||||
os.getenv("DEFAULT_MCP_SEMANTIC_FILTER_SIMILARITY_THRESHOLD", 0.3)
|
||||
)
|
||||
MAX_MCP_SEMANTIC_FILTER_TOOLS_HEADER_LENGTH = int(
|
||||
os.getenv("MAX_MCP_SEMANTIC_FILTER_TOOLS_HEADER_LENGTH", 150)
|
||||
)
|
||||
|
||||
LITELLM_UI_ALLOW_HEADERS = [
|
||||
"x-litellm-semantic-filter",
|
||||
"x-litellm-semantic-filter-tools",
|
||||
]
|
||||
|
||||
# Gemini model-specific minimal thinking budget constants
|
||||
DEFAULT_REASONING_EFFORT_MINIMAL_THINKING_BUDGET_GEMINI_2_5_FLASH = int(
|
||||
os.getenv("DEFAULT_REASONING_EFFORT_MINIMAL_THINKING_BUDGET_GEMINI_2_5_FLASH", 1)
|
||||
|
|
@ -85,6 +104,9 @@ DEFAULT_REASONING_EFFORT_MINIMAL_THINKING_BUDGET = int(
|
|||
os.getenv("DEFAULT_REASONING_EFFORT_MINIMAL_THINKING_BUDGET", 128)
|
||||
)
|
||||
|
||||
# Provider-specific API base URLs
|
||||
XAI_API_BASE = "https://api.x.ai/v1"
|
||||
|
||||
DEFAULT_REASONING_EFFORT_LOW_THINKING_BUDGET = int(
|
||||
os.getenv("DEFAULT_REASONING_EFFORT_LOW_THINKING_BUDGET", 1024)
|
||||
)
|
||||
|
|
@ -948,6 +970,8 @@ BEDROCK_CONVERSE_MODELS = [
|
|||
"openai.gpt-oss-120b-1:0",
|
||||
"anthropic.claude-haiku-4-5-20251001-v1:0",
|
||||
"anthropic.claude-sonnet-4-5-20250929-v1:0",
|
||||
"anthropic.claude-opus-4-6-v1:0",
|
||||
"anthropic.claude-opus-4-6-v1",
|
||||
"anthropic.claude-opus-4-1-20250805-v1:0",
|
||||
"anthropic.claude-opus-4-20250514-v1:0",
|
||||
"anthropic.claude-sonnet-4-20250514-v1:0",
|
||||
|
|
|
|||
|
|
@ -1378,6 +1378,11 @@ Model Info:
|
|||
"""
|
||||
if self.alerting is None:
|
||||
return
|
||||
|
||||
# Start periodic flush if not already started
|
||||
if not self.periodic_started and self.alerting is not None and len(self.alerting) > 0:
|
||||
asyncio.create_task(self.periodic_flush())
|
||||
self.periodic_started = True
|
||||
|
||||
if (
|
||||
"webhook" in self.alerting
|
||||
|
|
|
|||
|
|
@ -475,11 +475,18 @@ class CustomGuardrail(CustomLogger):
|
|||
guardrail_config: DynamicGuardrailParams = DynamicGuardrailParams(
|
||||
**guardrail[self.guardrail_name]
|
||||
)
|
||||
extra_body = guardrail_config.get("extra_body", {})
|
||||
if self._validate_premium_user() is not True:
|
||||
if isinstance(extra_body, dict) and extra_body:
|
||||
verbose_logger.warning(
|
||||
"Guardrail %s: ignoring dynamic extra_body keys %s because premium_user is False",
|
||||
self.guardrail_name,
|
||||
list(extra_body.keys()),
|
||||
)
|
||||
return {}
|
||||
|
||||
# Return the extra_body if it exists, otherwise empty dict
|
||||
return guardrail_config.get("extra_body", {})
|
||||
return extra_body
|
||||
|
||||
return {}
|
||||
|
||||
|
|
|
|||
|
|
@ -85,6 +85,30 @@ SOFT_BUDGET_ALERT_EMAIL_TEMPLATE = """
|
|||
The LiteLLM team <br />
|
||||
"""
|
||||
|
||||
TEAM_SOFT_BUDGET_ALERT_EMAIL_TEMPLATE = """
|
||||
<img src="{email_logo_url}" alt="LiteLLM Logo" width="150" height="50" />
|
||||
|
||||
<p> Hi {team_alias} team member, <br/>
|
||||
|
||||
Your LiteLLM team has crossed its <b>soft budget limit of {soft_budget}</b>. <br /> <br />
|
||||
|
||||
<b>Current Spend:</b> {spend} <br />
|
||||
<b>Soft Budget:</b> {soft_budget} <br />
|
||||
{max_budget_info}
|
||||
|
||||
<p style="color: #dc2626; font-weight: 500;">
|
||||
⚠️ Note: Your API requests will continue to work, but you should monitor your usage closely.
|
||||
If you reach your maximum budget, requests will be rejected.
|
||||
</p>
|
||||
|
||||
You can view your usage and manage your budget in the <a href="{base_url}">LiteLLM Dashboard</a>. <br /> <br />
|
||||
|
||||
If you have any questions, please send an email to {email_support_contact} <br /> <br />
|
||||
|
||||
Best, <br />
|
||||
The LiteLLM team <br />
|
||||
"""
|
||||
|
||||
MAX_BUDGET_ALERT_EMAIL_TEMPLATE = """
|
||||
<img src="{email_logo_url}" alt="LiteLLM Logo" width="150" height="50" />
|
||||
|
||||
|
|
|
|||
|
|
@ -8,9 +8,8 @@ from litellm.integrations.arize import _utils
|
|||
from litellm.integrations.langfuse.langfuse_otel_attributes import (
|
||||
LangfuseLLMObsOTELAttributes,
|
||||
)
|
||||
from litellm.integrations.opentelemetry import OpenTelemetry
|
||||
from litellm.integrations.opentelemetry import OpenTelemetry, OpenTelemetryConfig
|
||||
from litellm.types.integrations.langfuse_otel import (
|
||||
LangfuseOtelConfig,
|
||||
LangfuseSpanAttributes,
|
||||
)
|
||||
from litellm.types.utils import StandardCallbackDynamicParams
|
||||
|
|
@ -18,17 +17,8 @@ from litellm.types.utils import StandardCallbackDynamicParams
|
|||
if TYPE_CHECKING:
|
||||
from opentelemetry.trace import Span as _Span
|
||||
|
||||
from litellm.integrations.opentelemetry import (
|
||||
OpenTelemetryConfig as _OpenTelemetryConfig,
|
||||
)
|
||||
from litellm.types.integrations.arize import Protocol as _Protocol
|
||||
|
||||
Protocol = _Protocol
|
||||
OpenTelemetryConfig = _OpenTelemetryConfig
|
||||
Span = Union[_Span, Any]
|
||||
else:
|
||||
Protocol = Any
|
||||
OpenTelemetryConfig = Any
|
||||
Span = Any
|
||||
|
||||
|
||||
|
|
@ -37,8 +27,12 @@ LANGFUSE_CLOUD_US_ENDPOINT = "https://us.cloud.langfuse.com/api/public/otel"
|
|||
|
||||
|
||||
class LangfuseOtelLogger(OpenTelemetry):
|
||||
def __init__(self, *args, **kwargs):
|
||||
super().__init__(*args, **kwargs)
|
||||
def __init__(self, config=None, *args, **kwargs):
|
||||
# Prevent LangfuseOtelLogger from modifying global environment variables by constructing config manually
|
||||
# and passing it to the parent OpenTelemetry class
|
||||
if config is None:
|
||||
config = self._create_open_telemetry_config_from_langfuse_env()
|
||||
super().__init__(config=config, *args, **kwargs)
|
||||
|
||||
@staticmethod
|
||||
def set_langfuse_otel_attributes(span: Span, kwargs, response_obj):
|
||||
|
|
@ -114,6 +108,10 @@ class LangfuseOtelLogger(OpenTelemetry):
|
|||
for key, enum_attr in mapping.items():
|
||||
if key in metadata and metadata[key] is not None:
|
||||
value = metadata[key]
|
||||
if key == "trace_id" and isinstance(value, str):
|
||||
# trace_id must be 32 hex char no dashes for langfuse : Litellm sends uuid with dashes (might be breaking at some point)
|
||||
value = value.replace("-", "")
|
||||
|
||||
if isinstance(value, (list, dict)):
|
||||
try:
|
||||
value = json.dumps(value)
|
||||
|
|
@ -265,8 +263,47 @@ class LangfuseOtelLogger(OpenTelemetry):
|
|||
"""
|
||||
return os.environ.get("LANGFUSE_OTEL_HOST") or os.environ.get("LANGFUSE_HOST")
|
||||
|
||||
def _create_open_telemetry_config_from_langfuse_env(self) -> OpenTelemetryConfig:
|
||||
"""
|
||||
Creates OpenTelemetryConfig from Langfuse environment variables.
|
||||
Does NOT modify global environment variables.
|
||||
"""
|
||||
from litellm.integrations.opentelemetry import OpenTelemetryConfig
|
||||
|
||||
public_key = os.environ.get("LANGFUSE_PUBLIC_KEY", None)
|
||||
secret_key = os.environ.get("LANGFUSE_SECRET_KEY", None)
|
||||
|
||||
if not public_key or not secret_key:
|
||||
# If no keys, return default from env (likely logging to console or something else)
|
||||
return OpenTelemetryConfig.from_env()
|
||||
|
||||
# Determine endpoint - default to US cloud
|
||||
langfuse_host = LangfuseOtelLogger._get_langfuse_otel_host()
|
||||
|
||||
if langfuse_host:
|
||||
# If LANGFUSE_HOST is provided, construct OTEL endpoint from it
|
||||
if not langfuse_host.startswith("http"):
|
||||
langfuse_host = "https://" + langfuse_host
|
||||
endpoint = f"{langfuse_host.rstrip('/')}/api/public/otel"
|
||||
verbose_logger.debug(f"Using Langfuse OTEL endpoint from host: {endpoint}")
|
||||
else:
|
||||
# Default to US cloud endpoint
|
||||
endpoint = LANGFUSE_CLOUD_US_ENDPOINT
|
||||
verbose_logger.debug(f"Using Langfuse US cloud endpoint: {endpoint}")
|
||||
|
||||
auth_header = LangfuseOtelLogger._get_langfuse_authorization_header(
|
||||
public_key=public_key, secret_key=secret_key
|
||||
)
|
||||
otlp_auth_headers = f"Authorization={auth_header}"
|
||||
|
||||
return OpenTelemetryConfig(
|
||||
exporter="otlp_http",
|
||||
endpoint=endpoint,
|
||||
headers=otlp_auth_headers,
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def get_langfuse_otel_config() -> LangfuseOtelConfig:
|
||||
def get_langfuse_otel_config() -> "OpenTelemetryConfig":
|
||||
"""
|
||||
Retrieves the Langfuse OpenTelemetry configuration based on environment variables.
|
||||
|
||||
|
|
@ -276,7 +313,7 @@ class LangfuseOtelLogger(OpenTelemetry):
|
|||
LANGFUSE_HOST: Optional. Custom Langfuse host URL. Defaults to US cloud.
|
||||
|
||||
Returns:
|
||||
LangfuseOtelConfig: A Pydantic model containing Langfuse OTEL configuration.
|
||||
OpenTelemetryConfig: A Pydantic model containing Langfuse OTEL configuration.
|
||||
|
||||
Raises:
|
||||
ValueError: If required keys are missing.
|
||||
|
|
@ -308,12 +345,14 @@ class LangfuseOtelLogger(OpenTelemetry):
|
|||
)
|
||||
otlp_auth_headers = f"Authorization={auth_header}"
|
||||
|
||||
# Set standard OTEL environment variables
|
||||
os.environ["OTEL_EXPORTER_OTLP_ENDPOINT"] = endpoint
|
||||
os.environ["OTEL_EXPORTER_OTLP_HEADERS"] = otlp_auth_headers
|
||||
# Prevent modification of global env vars which causes leakage
|
||||
# os.environ["OTEL_EXPORTER_OTLP_ENDPOINT"] = endpoint
|
||||
# os.environ["OTEL_EXPORTER_OTLP_HEADERS"] = otlp_auth_headers
|
||||
|
||||
return LangfuseOtelConfig(
|
||||
otlp_auth_headers=otlp_auth_headers, protocol="otlp_http"
|
||||
return OpenTelemetryConfig(
|
||||
exporter="otlp_http",
|
||||
endpoint=endpoint,
|
||||
headers=otlp_auth_headers,
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
|
|
|
|||
|
|
@ -599,9 +599,9 @@ class OpenTelemetry(CustomLogger):
|
|||
|
||||
def _get_dynamic_otel_headers_from_kwargs(self, kwargs) -> Optional[dict]:
|
||||
"""Extract dynamic headers from kwargs if available."""
|
||||
standard_callback_dynamic_params: Optional[StandardCallbackDynamicParams] = (
|
||||
kwargs.get("standard_callback_dynamic_params")
|
||||
)
|
||||
standard_callback_dynamic_params: Optional[
|
||||
StandardCallbackDynamicParams
|
||||
] = kwargs.get("standard_callback_dynamic_params")
|
||||
|
||||
if not standard_callback_dynamic_params:
|
||||
return None
|
||||
|
|
@ -619,7 +619,9 @@ class OpenTelemetry(CustomLogger):
|
|||
# Prevents thread exhaustion by reusing providers for the same credential sets (e.g. per-team keys)
|
||||
cache_key = str(sorted(dynamic_headers.items()))
|
||||
if cache_key in self._tracer_provider_cache:
|
||||
return self._tracer_provider_cache[cache_key].get_tracer(LITELLM_TRACER_NAME)
|
||||
return self._tracer_provider_cache[cache_key].get_tracer(
|
||||
LITELLM_TRACER_NAME
|
||||
)
|
||||
|
||||
# Create a temporary tracer provider with dynamic headers
|
||||
temp_provider = TracerProvider(resource=self._get_litellm_resource(self.config))
|
||||
|
|
@ -674,7 +676,10 @@ class OpenTelemetry(CustomLogger):
|
|||
kwargs, response_obj, start_time, end_time, span
|
||||
)
|
||||
# Ensure proxy-request parent span is annotated with the actual operation kind
|
||||
if parent_span is not None and parent_span.name == LITELLM_PROXY_REQUEST_SPAN_NAME:
|
||||
if (
|
||||
parent_span is not None
|
||||
and parent_span.name == LITELLM_PROXY_REQUEST_SPAN_NAME
|
||||
):
|
||||
self.set_attributes(parent_span, kwargs, response_obj)
|
||||
else:
|
||||
# Do not create primary span (keep hierarchy shallow when parent exists)
|
||||
|
|
@ -1003,14 +1008,11 @@ class OpenTelemetry(CustomLogger):
|
|||
# TODO: Refactor to use the proper OTEL Logs API instead of directly creating SDK LogRecords
|
||||
|
||||
from opentelemetry._logs import SeverityNumber, get_logger, get_logger_provider
|
||||
|
||||
try:
|
||||
from opentelemetry.sdk._logs import (
|
||||
LogRecord as SdkLogRecord, # type: ignore[attr-defined] # OTEL < 1.39.0
|
||||
)
|
||||
from opentelemetry.sdk._logs import LogRecord as SdkLogRecord # type: ignore[attr-defined] # OTEL < 1.39.0
|
||||
except ImportError:
|
||||
from opentelemetry.sdk._logs._internal import (
|
||||
LogRecord as SdkLogRecord, # OTEL >= 1.39.0
|
||||
)
|
||||
from opentelemetry.sdk._logs._internal import LogRecord as SdkLogRecord # type: ignore[attr-defined, no-redef] # OTEL >= 1.39.0
|
||||
|
||||
otel_logger = get_logger(LITELLM_LOGGER_NAME)
|
||||
|
||||
|
|
@ -1618,7 +1620,6 @@ class OpenTelemetry(CustomLogger):
|
|||
|
||||
for idx, choice in enumerate(response_obj.get("choices")):
|
||||
if choice.get("finish_reason"):
|
||||
|
||||
message = choice.get("message")
|
||||
tool_calls = message.get("tool_calls")
|
||||
if tool_calls:
|
||||
|
|
@ -1631,7 +1632,9 @@ class OpenTelemetry(CustomLogger):
|
|||
)
|
||||
|
||||
except Exception as e:
|
||||
self.handle_callback_failure(callback_name=self.callback_name or "opentelemetry")
|
||||
self.handle_callback_failure(
|
||||
callback_name=self.callback_name or "opentelemetry"
|
||||
)
|
||||
verbose_logger.exception(
|
||||
"OpenTelemetry logging error in set_attributes %s", str(e)
|
||||
)
|
||||
|
|
@ -1722,6 +1725,7 @@ class OpenTelemetry(CustomLogger):
|
|||
|
||||
def set_raw_request_attributes(self, span: Span, kwargs, response_obj):
|
||||
try:
|
||||
self.set_attributes(span, kwargs, response_obj)
|
||||
kwargs.get("optional_params", {})
|
||||
litellm_params = kwargs.get("litellm_params", {}) or {}
|
||||
custom_llm_provider = litellm_params.get("custom_llm_provider", "Unknown")
|
||||
|
|
|
|||
|
|
@ -1,6 +1,7 @@
|
|||
# used for /metrics endpoint on LiteLLM Proxy
|
||||
#### What this does ####
|
||||
# On success, log events to Prometheus
|
||||
import asyncio
|
||||
import os
|
||||
import sys
|
||||
from datetime import datetime, timedelta
|
||||
|
|
@ -1188,28 +1189,34 @@ class PrometheusLogger(CustomLogger):
|
|||
_user_spend = _metadata.get("user_api_key_user_spend", None)
|
||||
_user_max_budget = _metadata.get("user_api_key_user_max_budget", None)
|
||||
|
||||
await self._set_api_key_budget_metrics_after_api_request(
|
||||
user_api_key=user_api_key,
|
||||
user_api_key_alias=user_api_key_alias,
|
||||
response_cost=response_cost,
|
||||
key_max_budget=_api_key_max_budget,
|
||||
key_spend=_api_key_spend,
|
||||
)
|
||||
|
||||
await self._set_team_budget_metrics_after_api_request(
|
||||
user_api_team=user_api_team,
|
||||
user_api_team_alias=user_api_team_alias,
|
||||
team_spend=_team_spend,
|
||||
team_max_budget=_team_max_budget,
|
||||
response_cost=response_cost,
|
||||
)
|
||||
|
||||
await self._set_user_budget_metrics_after_api_request(
|
||||
user_id=user_id,
|
||||
user_spend=_user_spend,
|
||||
user_max_budget=_user_max_budget,
|
||||
response_cost=response_cost,
|
||||
results = await asyncio.gather(
|
||||
self._set_api_key_budget_metrics_after_api_request(
|
||||
user_api_key=user_api_key,
|
||||
user_api_key_alias=user_api_key_alias,
|
||||
response_cost=response_cost,
|
||||
key_max_budget=_api_key_max_budget,
|
||||
key_spend=_api_key_spend,
|
||||
),
|
||||
self._set_team_budget_metrics_after_api_request(
|
||||
user_api_team=user_api_team,
|
||||
user_api_team_alias=user_api_team_alias,
|
||||
team_spend=_team_spend,
|
||||
team_max_budget=_team_max_budget,
|
||||
response_cost=response_cost,
|
||||
),
|
||||
self._set_user_budget_metrics_after_api_request(
|
||||
user_id=user_id,
|
||||
user_spend=_user_spend,
|
||||
user_max_budget=_user_max_budget,
|
||||
response_cost=response_cost,
|
||||
),
|
||||
return_exceptions=True,
|
||||
)
|
||||
for i, r in enumerate(results):
|
||||
if isinstance(r, Exception):
|
||||
verbose_logger.debug(
|
||||
f"[Non-Blocking] Prometheus: Budget metric lookup {['key', 'team', 'user'][i]} failed: {r}"
|
||||
)
|
||||
|
||||
def _increment_top_level_request_and_spend_metrics(
|
||||
self,
|
||||
|
|
@ -1683,6 +1690,108 @@ class PrometheusLogger(CustomLogger):
|
|||
)
|
||||
pass
|
||||
|
||||
def _safe_get(self, obj: Any, key: str, default: Any = None) -> Any:
|
||||
"""Get value from dict or Pydantic model."""
|
||||
if obj is None:
|
||||
return default
|
||||
if isinstance(obj, dict):
|
||||
return obj.get(key, default)
|
||||
return getattr(obj, key, default)
|
||||
|
||||
def _extract_deployment_failure_label_values(
|
||||
self, request_kwargs: dict
|
||||
) -> Dict[str, Optional[str]]:
|
||||
"""
|
||||
Extract label values for deployment failure metrics from all available
|
||||
sources in request_kwargs. Falls back to litellm_params metadata and
|
||||
user_api_key_auth when standard_logging_payload has None values.
|
||||
"""
|
||||
standard_logging_payload = (
|
||||
request_kwargs.get("standard_logging_object", {}) or {}
|
||||
)
|
||||
_litellm_params = request_kwargs.get("litellm_params", {}) or {}
|
||||
_metadata_raw = self._safe_get(standard_logging_payload, "metadata") or {}
|
||||
if isinstance(_metadata_raw, dict):
|
||||
_metadata = _metadata_raw
|
||||
else:
|
||||
_metadata = {
|
||||
"user_api_key_alias": getattr(
|
||||
_metadata_raw, "user_api_key_alias", None
|
||||
),
|
||||
"user_api_key_team_id": getattr(
|
||||
_metadata_raw, "user_api_key_team_id", None
|
||||
),
|
||||
"user_api_key_team_alias": getattr(
|
||||
_metadata_raw, "user_api_key_team_alias", None
|
||||
),
|
||||
"user_api_key_hash": getattr(_metadata_raw, "user_api_key_hash", None),
|
||||
"requester_ip_address": getattr(
|
||||
_metadata_raw, "requester_ip_address", None
|
||||
),
|
||||
"user_agent": getattr(_metadata_raw, "user_agent", None),
|
||||
}
|
||||
_litellm_params_metadata = _litellm_params.get("metadata", {}) or {}
|
||||
|
||||
# Extract user_api_key_auth if present (proxy injects this, skipped in merge)
|
||||
user_api_key_auth = _litellm_params_metadata.get("user_api_key_auth")
|
||||
|
||||
def _get_api_key_alias() -> Optional[str]:
|
||||
val = _metadata.get("user_api_key_alias")
|
||||
if val is not None:
|
||||
return val
|
||||
val = _litellm_params_metadata.get("user_api_key_alias")
|
||||
if val is not None:
|
||||
return val
|
||||
if user_api_key_auth is not None:
|
||||
return getattr(user_api_key_auth, "key_alias", None)
|
||||
return None
|
||||
|
||||
def _get_team_id() -> Optional[str]:
|
||||
val = _metadata.get("user_api_key_team_id")
|
||||
if val is not None:
|
||||
return val
|
||||
val = _litellm_params_metadata.get("user_api_key_team_id")
|
||||
if val is not None:
|
||||
return val
|
||||
if user_api_key_auth is not None:
|
||||
return getattr(user_api_key_auth, "team_id", None)
|
||||
return None
|
||||
|
||||
def _get_team_alias() -> Optional[str]:
|
||||
val = _metadata.get("user_api_key_team_alias")
|
||||
if val is not None:
|
||||
return val
|
||||
val = _litellm_params_metadata.get("user_api_key_team_alias")
|
||||
if val is not None:
|
||||
return val
|
||||
if user_api_key_auth is not None:
|
||||
return getattr(user_api_key_auth, "team_alias", None)
|
||||
return None
|
||||
|
||||
def _get_hashed_api_key() -> Optional[str]:
|
||||
val = _metadata.get("user_api_key_hash")
|
||||
if val is not None:
|
||||
return val
|
||||
val = _litellm_params_metadata.get("user_api_key_hash")
|
||||
if val is not None:
|
||||
return val
|
||||
if user_api_key_auth is not None:
|
||||
return getattr(user_api_key_auth, "api_key", None) or getattr(
|
||||
user_api_key_auth, "api_key_hash", None
|
||||
)
|
||||
return None
|
||||
|
||||
return {
|
||||
"api_key_alias": _get_api_key_alias(),
|
||||
"team": _get_team_id(),
|
||||
"team_alias": _get_team_alias(),
|
||||
"hashed_api_key": _get_hashed_api_key(),
|
||||
"client_ip": _metadata.get("requester_ip_address")
|
||||
or _litellm_params_metadata.get("requester_ip_address"),
|
||||
"user_agent": _metadata.get("user_agent")
|
||||
or _litellm_params_metadata.get("user_agent"),
|
||||
}
|
||||
|
||||
def set_llm_deployment_failure_metrics(self, request_kwargs: dict):
|
||||
"""
|
||||
Sets Failure metrics when an LLM API call fails
|
||||
|
|
@ -1707,6 +1816,21 @@ class PrometheusLogger(CustomLogger):
|
|||
model_id = standard_logging_payload.get("model_id", None)
|
||||
exception = request_kwargs.get("exception", None)
|
||||
|
||||
# Fallback: model_id from litellm_metadata.model_info
|
||||
if model_id is None:
|
||||
_model_info = (
|
||||
(_litellm_params.get("litellm_metadata") or {}).get("model_info")
|
||||
or (_litellm_params.get("metadata") or {}).get("model_info")
|
||||
or {}
|
||||
)
|
||||
model_id = _model_info.get("id")
|
||||
|
||||
# Fallback: model_group from litellm_metadata
|
||||
if model_group is None:
|
||||
model_group = (_litellm_params.get("litellm_metadata") or {}).get(
|
||||
"model_group"
|
||||
) or (_litellm_params.get("metadata") or {}).get("model_group")
|
||||
|
||||
llm_provider = _litellm_params.get("custom_llm_provider", None)
|
||||
|
||||
if self._should_skip_metrics_for_invalid_key(
|
||||
|
|
@ -1714,9 +1838,37 @@ class PrometheusLogger(CustomLogger):
|
|||
standard_logging_payload=standard_logging_payload,
|
||||
):
|
||||
return
|
||||
hashed_api_key = standard_logging_payload.get("metadata", {}).get(
|
||||
|
||||
# Extract context labels from all available sources (fix for None labels)
|
||||
fallback_values = self._extract_deployment_failure_label_values(
|
||||
request_kwargs
|
||||
)
|
||||
_metadata = standard_logging_payload.get("metadata", {}) or {}
|
||||
hashed_api_key = fallback_values.get("hashed_api_key") or _metadata.get(
|
||||
"user_api_key_hash"
|
||||
)
|
||||
api_key_alias = fallback_values.get("api_key_alias") or _metadata.get(
|
||||
"user_api_key_alias"
|
||||
)
|
||||
team = fallback_values.get("team") or _metadata.get("user_api_key_team_id")
|
||||
team_alias = fallback_values.get("team_alias") or _metadata.get(
|
||||
"user_api_key_team_alias"
|
||||
)
|
||||
client_ip = fallback_values.get("client_ip") or _metadata.get(
|
||||
"requester_ip_address"
|
||||
)
|
||||
user_agent = fallback_values.get("user_agent") or _metadata.get(
|
||||
"user_agent"
|
||||
)
|
||||
|
||||
# exception_status: prefer status_code, fallback to exception class for known types
|
||||
exception_status = None
|
||||
if exception is not None:
|
||||
exception_status = str(getattr(exception, "status_code", None))
|
||||
if exception_status == "None" or not exception_status:
|
||||
code = getattr(exception, "code", None)
|
||||
if code is not None:
|
||||
exception_status = str(code)
|
||||
|
||||
# Create enum_values for the label factory (always create for use in different metrics)
|
||||
enum_values = UserAPIKeyLabelValues(
|
||||
|
|
@ -1724,26 +1876,18 @@ class PrometheusLogger(CustomLogger):
|
|||
model_id=model_id,
|
||||
api_base=api_base,
|
||||
api_provider=llm_provider,
|
||||
exception_status=(
|
||||
str(getattr(exception, "status_code", None)) if exception else None
|
||||
),
|
||||
exception_status=exception_status,
|
||||
exception_class=(
|
||||
self._get_exception_class_name(exception) if exception else None
|
||||
),
|
||||
requested_model=model_group,
|
||||
requested_model=model_group or litellm_model_name,
|
||||
hashed_api_key=hashed_api_key,
|
||||
api_key_alias=standard_logging_payload["metadata"][
|
||||
"user_api_key_alias"
|
||||
],
|
||||
team=standard_logging_payload["metadata"]["user_api_key_team_id"],
|
||||
team_alias=standard_logging_payload["metadata"][
|
||||
"user_api_key_team_alias"
|
||||
],
|
||||
api_key_alias=api_key_alias,
|
||||
team=team,
|
||||
team_alias=team_alias,
|
||||
tags=standard_logging_payload.get("request_tags", []),
|
||||
client_ip=standard_logging_payload["metadata"].get(
|
||||
"requester_ip_address"
|
||||
),
|
||||
user_agent=standard_logging_payload["metadata"].get("user_agent"),
|
||||
client_ip=client_ip,
|
||||
user_agent=user_agent,
|
||||
)
|
||||
|
||||
"""
|
||||
|
|
@ -2761,12 +2905,14 @@ class PrometheusLogger(CustomLogger):
|
|||
max_budget=max_budget,
|
||||
)
|
||||
try:
|
||||
# Note: Setting check_db_only=True bypasses cache and hits DB on every request,
|
||||
# causing huge latency increase and CPU spikes. Keep check_db_only=False.
|
||||
user_info = await get_user_object(
|
||||
user_id=user_id,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
user_id_upsert=False,
|
||||
check_db_only=True,
|
||||
check_db_only=False,
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_logger.debug(
|
||||
|
|
|
|||
|
|
@ -94,8 +94,8 @@ def map_finish_reason(
|
|||
return "length"
|
||||
elif finish_reason == "tool_use": # anthropic
|
||||
return "tool_calls"
|
||||
elif finish_reason == "content_filtered":
|
||||
return "content_filter"
|
||||
elif finish_reason == "compaction":
|
||||
return "length"
|
||||
return finish_reason
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -1,8 +1,35 @@
|
|||
from typing import Dict, Optional
|
||||
|
||||
from litellm.secret_managers.main import get_secret_str
|
||||
from litellm.types.utils import StandardCallbackDynamicParams
|
||||
|
||||
# Hardcoded list of supported callback params to avoid runtime inspection issues with TypedDict
|
||||
_supported_callback_params = [
|
||||
"langfuse_public_key",
|
||||
"langfuse_secret",
|
||||
"langfuse_secret_key",
|
||||
"langfuse_host",
|
||||
"langfuse_prompt_version",
|
||||
"gcs_bucket_name",
|
||||
"gcs_path_service_account",
|
||||
"langsmith_api_key",
|
||||
"langsmith_project",
|
||||
"langsmith_base_url",
|
||||
"langsmith_sampling_rate",
|
||||
"langsmith_tenant_id",
|
||||
"humanloop_api_key",
|
||||
"arize_api_key",
|
||||
"arize_space_key",
|
||||
"arize_space_id",
|
||||
"posthog_api_key",
|
||||
"posthog_host",
|
||||
"braintrust_api_key",
|
||||
"braintrust_project",
|
||||
"braintrust_host",
|
||||
"slack_webhook_url",
|
||||
"lunary_public_key",
|
||||
"turn_off_message_logging",
|
||||
]
|
||||
|
||||
|
||||
def initialize_standard_callback_dynamic_params(
|
||||
kwargs: Optional[Dict] = None,
|
||||
|
|
@ -15,13 +42,10 @@ def initialize_standard_callback_dynamic_params(
|
|||
|
||||
standard_callback_dynamic_params = StandardCallbackDynamicParams()
|
||||
if kwargs:
|
||||
_supported_callback_params = (
|
||||
StandardCallbackDynamicParams.__annotations__.keys()
|
||||
)
|
||||
|
||||
# 1. Check top-level kwargs
|
||||
for param in _supported_callback_params:
|
||||
if param in kwargs:
|
||||
_param_value = kwargs.pop(param)
|
||||
_param_value = kwargs.get(param)
|
||||
if (
|
||||
_param_value is not None
|
||||
and isinstance(_param_value, str)
|
||||
|
|
@ -30,4 +54,22 @@ def initialize_standard_callback_dynamic_params(
|
|||
_param_value = get_secret_str(secret_name=_param_value)
|
||||
standard_callback_dynamic_params[param] = _param_value # type: ignore
|
||||
|
||||
# 2. Fallback: check "metadata" or "litellm_params" -> "metadata"
|
||||
metadata = (kwargs.get("metadata") or {}).copy()
|
||||
litellm_params = kwargs.get("litellm_params") or {}
|
||||
if isinstance(litellm_params, dict):
|
||||
metadata.update(litellm_params.get("metadata") or {})
|
||||
|
||||
if isinstance(metadata, dict):
|
||||
for param in _supported_callback_params:
|
||||
if param not in standard_callback_dynamic_params and param in metadata:
|
||||
_param_value = metadata.get(param)
|
||||
if (
|
||||
_param_value is not None
|
||||
and isinstance(_param_value, str)
|
||||
and "os.environ/" in _param_value
|
||||
):
|
||||
_param_value = get_secret_str(secret_name=_param_value)
|
||||
standard_callback_dynamic_params[param] = _param_value # type: ignore
|
||||
|
||||
return standard_callback_dynamic_params
|
||||
|
|
|
|||
|
|
@ -2435,6 +2435,36 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
standard_built_in_tools_params=self.standard_built_in_tools_params,
|
||||
)
|
||||
|
||||
# print standard logging payload
|
||||
if (
|
||||
standard_logging_payload := self.model_call_details.get(
|
||||
"standard_logging_object"
|
||||
)
|
||||
) is not None:
|
||||
emit_standard_logging_payload(standard_logging_payload)
|
||||
elif self.call_type == "pass_through_endpoint":
|
||||
print_verbose(
|
||||
"Async success callbacks: Got a pass-through endpoint response"
|
||||
)
|
||||
|
||||
self.model_call_details["async_complete_streaming_response"] = result
|
||||
|
||||
# cost calculation not possible for pass-through
|
||||
self.model_call_details["response_cost"] = None
|
||||
|
||||
## STANDARDIZED LOGGING PAYLOAD
|
||||
self.model_call_details[
|
||||
"standard_logging_object"
|
||||
] = get_standard_logging_object_payload(
|
||||
kwargs=self.model_call_details,
|
||||
init_response_obj=result,
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
logging_obj=self,
|
||||
status="success",
|
||||
standard_built_in_tools_params=self.standard_built_in_tools_params,
|
||||
)
|
||||
|
||||
# print standard logging payload
|
||||
if (
|
||||
standard_logging_payload := self.model_call_details.get(
|
||||
|
|
@ -3887,18 +3917,6 @@ def _init_custom_logger_compatible_class( # noqa: PLR0915
|
|||
return langfuse_logger # type: ignore
|
||||
elif logging_integration == "langfuse_otel":
|
||||
from litellm.integrations.langfuse.langfuse_otel import LangfuseOtelLogger
|
||||
from litellm.integrations.opentelemetry import (
|
||||
OpenTelemetry,
|
||||
OpenTelemetryConfig,
|
||||
)
|
||||
|
||||
langfuse_otel_config = LangfuseOtelLogger.get_langfuse_otel_config()
|
||||
|
||||
# The endpoint and headers are now set as environment variables by get_langfuse_otel_config()
|
||||
otel_config = OpenTelemetryConfig(
|
||||
exporter=langfuse_otel_config.protocol,
|
||||
headers=langfuse_otel_config.otlp_auth_headers,
|
||||
)
|
||||
|
||||
for callback in _in_memory_loggers:
|
||||
if (
|
||||
|
|
@ -3906,8 +3924,10 @@ def _init_custom_logger_compatible_class( # noqa: PLR0915
|
|||
and callback.callback_name == "langfuse_otel"
|
||||
):
|
||||
return callback # type: ignore
|
||||
# Allow LangfuseOtelLogger to initialize its own config safely
|
||||
# This prevents startup crashes if LANGFUSE keys are not in env (e.g. for dynamic usage)
|
||||
_otel_logger = LangfuseOtelLogger(
|
||||
config=otel_config, callback_name="langfuse_otel"
|
||||
config=None, callback_name="langfuse_otel"
|
||||
)
|
||||
_in_memory_loggers.append(_otel_logger)
|
||||
return _otel_logger # type: ignore
|
||||
|
|
|
|||
|
|
@ -215,6 +215,9 @@ def _get_token_base_cost(
|
|||
cache_creation_tiered_key = (
|
||||
f"cache_creation_input_token_cost_above_{threshold_str}_tokens"
|
||||
)
|
||||
cache_creation_1hr_tiered_key = (
|
||||
f"cache_creation_input_token_cost_above_1hr_above_{threshold_str}_tokens"
|
||||
)
|
||||
cache_read_tiered_key = (
|
||||
f"cache_read_input_token_cost_above_{threshold_str}_tokens"
|
||||
)
|
||||
|
|
@ -229,6 +232,16 @@ def _get_token_base_cost(
|
|||
),
|
||||
)
|
||||
|
||||
if cache_creation_1hr_tiered_key in model_info:
|
||||
cache_creation_cost_above_1hr = cast(
|
||||
float,
|
||||
_get_cost_per_unit(
|
||||
model_info,
|
||||
cache_creation_1hr_tiered_key,
|
||||
cache_creation_cost_above_1hr,
|
||||
),
|
||||
)
|
||||
|
||||
if cache_read_tiered_key in model_info:
|
||||
cache_read_cost = cast(
|
||||
float,
|
||||
|
|
|
|||
|
|
@ -114,6 +114,27 @@ class LoggingCallbackManager:
|
|||
for c in remove_list:
|
||||
callback_list.remove(c)
|
||||
|
||||
def remove_callbacks_by_type(self, callback_list, callback_type):
|
||||
"""
|
||||
Remove all callbacks of a specific type from a callback list.
|
||||
|
||||
Args:
|
||||
callback_list: The list to remove callbacks from (e.g., litellm.callbacks)
|
||||
callback_type: The class type to match (e.g., SemanticToolFilterHook)
|
||||
|
||||
Example:
|
||||
litellm.logging_callback_manager.remove_callbacks_by_type(
|
||||
litellm.callbacks, SemanticToolFilterHook
|
||||
)
|
||||
"""
|
||||
if not isinstance(callback_list, list):
|
||||
return
|
||||
|
||||
remove_list = [c for c in callback_list if isinstance(c, callback_type)]
|
||||
|
||||
for c in remove_list:
|
||||
callback_list.remove(c)
|
||||
|
||||
def _add_string_callback_to_list(
|
||||
self, callback: str, parent_list: List[Union[CustomLogger, Callable, str]]
|
||||
):
|
||||
|
|
|
|||
|
|
@ -17,15 +17,16 @@ from litellm.types.rerank import RerankRequest
|
|||
|
||||
|
||||
class ModelParamHelper:
|
||||
# Cached at class level — deterministic set built from static OpenAI type annotations
|
||||
_relevant_logging_args: frozenset = frozenset()
|
||||
|
||||
@staticmethod
|
||||
def get_standard_logging_model_parameters(
|
||||
model_parameters: dict,
|
||||
) -> dict:
|
||||
""" """
|
||||
standard_logging_model_parameters: dict = {}
|
||||
supported_model_parameters = (
|
||||
ModelParamHelper._get_relevant_args_to_use_for_logging()
|
||||
)
|
||||
supported_model_parameters = ModelParamHelper._relevant_logging_args
|
||||
|
||||
for key, value in model_parameters.items():
|
||||
if key in supported_model_parameters:
|
||||
|
|
@ -172,3 +173,8 @@ class ModelParamHelper:
|
|||
Get the kwargs to exclude from the cache key
|
||||
"""
|
||||
return set(["metadata"])
|
||||
|
||||
|
||||
ModelParamHelper._relevant_logging_args = frozenset(
|
||||
ModelParamHelper._get_relevant_args_to_use_for_logging()
|
||||
)
|
||||
|
|
|
|||
|
|
@ -443,13 +443,21 @@ def update_messages_with_model_file_ids(
|
|||
|
||||
def update_responses_input_with_model_file_ids(
|
||||
input: Any,
|
||||
model_id: Optional[str] = None,
|
||||
model_file_id_mapping: Optional[Dict[str, Dict[str, str]]] = None,
|
||||
) -> Union[str, List[Dict[str, Any]]]:
|
||||
"""
|
||||
Updates responses API input with provider-specific file IDs.
|
||||
File IDs are always inside the content array, not as direct input_file items.
|
||||
|
||||
For managed files (unified file IDs), decodes the base64-encoded unified file ID
|
||||
and extracts the llm_output_file_id directly.
|
||||
For managed files (unified file IDs), uses model_file_id_mapping if provided,
|
||||
otherwise decodes the base64-encoded unified file ID and extracts the llm_output_file_id directly.
|
||||
|
||||
Args:
|
||||
input: The responses API input parameter
|
||||
model_id: The model ID to use for looking up provider-specific file IDs
|
||||
model_file_id_mapping: Dictionary mapping litellm file IDs to provider file IDs
|
||||
Format: {"litellm_file_id": {"model_id": "provider_file_id"}}
|
||||
"""
|
||||
from litellm.proxy.openai_files_endpoints.common_utils import (
|
||||
_is_base64_encoded_unified_file_id,
|
||||
|
|
@ -479,22 +487,35 @@ def update_responses_input_with_model_file_ids(
|
|||
):
|
||||
file_id = content_item.get("file_id")
|
||||
if file_id:
|
||||
# Check if this is a managed file ID (base64-encoded unified file ID)
|
||||
is_unified_file_id = _is_base64_encoded_unified_file_id(file_id)
|
||||
if is_unified_file_id:
|
||||
unified_file_id = convert_b64_uid_to_unified_uid(file_id)
|
||||
if "llm_output_file_id," in unified_file_id:
|
||||
provider_file_id = unified_file_id.split(
|
||||
"llm_output_file_id,"
|
||||
)[1].split(";")[0]
|
||||
else:
|
||||
# Fallback: keep original if we can't extract
|
||||
provider_file_id = file_id
|
||||
provider_file_id = file_id # Default to original
|
||||
|
||||
# Check if we have a mapping for this file ID
|
||||
if model_file_id_mapping and model_id and file_id in model_file_id_mapping:
|
||||
# Use the model-specific file ID from mapping
|
||||
provider_file_id = (
|
||||
model_file_id_mapping.get(file_id, {}).get(model_id)
|
||||
or file_id
|
||||
)
|
||||
updated_content_item = content_item.copy()
|
||||
updated_content_item["file_id"] = provider_file_id
|
||||
updated_content.append(updated_content_item)
|
||||
else:
|
||||
updated_content.append(content_item)
|
||||
# Check if this is a base64-encoded unified file ID without mapping
|
||||
is_unified_file_id = _is_base64_encoded_unified_file_id(file_id)
|
||||
if is_unified_file_id:
|
||||
# Fallback: decode unified file ID
|
||||
unified_file_id = convert_b64_uid_to_unified_uid(file_id)
|
||||
if "llm_output_file_id," in unified_file_id:
|
||||
provider_file_id = unified_file_id.split(
|
||||
"llm_output_file_id,"
|
||||
)[1].split(";")[0]
|
||||
|
||||
updated_content_item = content_item.copy()
|
||||
updated_content_item["file_id"] = provider_file_id
|
||||
updated_content.append(updated_content_item)
|
||||
else:
|
||||
# Not a managed file, keep as-is
|
||||
updated_content.append(content_item)
|
||||
else:
|
||||
updated_content.append(content_item)
|
||||
else:
|
||||
|
|
@ -506,6 +527,68 @@ def update_responses_input_with_model_file_ids(
|
|||
return updated_input
|
||||
|
||||
|
||||
def update_responses_tools_with_model_file_ids(
|
||||
tools: Optional[List[Dict[str, Any]]],
|
||||
model_id: Optional[str] = None,
|
||||
model_file_id_mapping: Optional[Dict[str, Dict[str, str]]] = None,
|
||||
) -> Optional[List[Dict[str, Any]]]:
|
||||
"""
|
||||
Updates responses API tools with provider-specific file IDs.
|
||||
|
||||
Handles code_interpreter tools with container.file_ids.
|
||||
|
||||
Args:
|
||||
tools: The responses API tools parameter
|
||||
model_id: The model ID to use for looking up provider-specific file IDs
|
||||
model_file_id_mapping: Dictionary mapping litellm file IDs to provider file IDs
|
||||
Format: {"litellm_file_id": {"model_id": "provider_file_id"}}
|
||||
"""
|
||||
if not tools or not isinstance(tools, list):
|
||||
return tools
|
||||
|
||||
if not model_file_id_mapping or not model_id:
|
||||
return tools
|
||||
|
||||
updated_tools = []
|
||||
for tool in tools:
|
||||
if not isinstance(tool, dict):
|
||||
updated_tools.append(tool)
|
||||
continue
|
||||
|
||||
updated_tool = tool.copy()
|
||||
|
||||
# Handle code_interpreter with container file_ids
|
||||
if tool.get("type") == "code_interpreter":
|
||||
container = tool.get("container")
|
||||
if isinstance(container, dict):
|
||||
container_file_ids = container.get("file_ids")
|
||||
if isinstance(container_file_ids, list):
|
||||
updated_file_ids = []
|
||||
for file_id in container_file_ids:
|
||||
if isinstance(file_id, str):
|
||||
# Check if we have a mapping for this file ID
|
||||
if file_id in model_file_id_mapping:
|
||||
# Map to provider-specific file ID
|
||||
provider_file_id = (
|
||||
model_file_id_mapping.get(file_id, {}).get(model_id)
|
||||
or file_id
|
||||
)
|
||||
updated_file_ids.append(provider_file_id)
|
||||
else:
|
||||
updated_file_ids.append(file_id)
|
||||
else:
|
||||
updated_file_ids.append(file_id)
|
||||
|
||||
# Update the tool with new file IDs
|
||||
updated_container = container.copy()
|
||||
updated_container["file_ids"] = updated_file_ids
|
||||
updated_tool["container"] = updated_container
|
||||
|
||||
updated_tools.append(updated_tool)
|
||||
|
||||
return updated_tools
|
||||
|
||||
|
||||
def extract_file_data(file_data: FileTypes) -> ExtractedFileData:
|
||||
"""
|
||||
Extracts and processes file data from various input formats.
|
||||
|
|
|
|||
|
|
@ -2190,6 +2190,16 @@ def anthropic_messages_pt( # noqa: PLR0915
|
|||
while msg_i < len(messages) and messages[msg_i]["role"] == "assistant":
|
||||
assistant_content_block: ChatCompletionAssistantMessage = messages[msg_i] # type: ignore
|
||||
|
||||
# Extract compaction_blocks from provider_specific_fields and add them first
|
||||
_provider_specific_fields_raw = assistant_content_block.get(
|
||||
"provider_specific_fields"
|
||||
)
|
||||
if isinstance(_provider_specific_fields_raw, dict):
|
||||
_compaction_blocks = _provider_specific_fields_raw.get("compaction_blocks")
|
||||
if _compaction_blocks and isinstance(_compaction_blocks, list):
|
||||
# Add compaction blocks at the beginning of assistant content : https://platform.claude.com/docs/en/build-with-claude/compaction
|
||||
assistant_content.extend(_compaction_blocks) # type: ignore
|
||||
|
||||
thinking_blocks = assistant_content_block.get("thinking_blocks", None)
|
||||
if (
|
||||
thinking_blocks is not None
|
||||
|
|
@ -3399,6 +3409,59 @@ def _convert_to_bedrock_tool_call_result(
|
|||
return content_block
|
||||
|
||||
|
||||
def _deduplicate_bedrock_content_blocks(
|
||||
blocks: List[BedrockContentBlock],
|
||||
block_key: str,
|
||||
id_key: str = "toolUseId",
|
||||
) -> List[BedrockContentBlock]:
|
||||
"""
|
||||
Remove duplicate content blocks that share the same ID under ``block_key``.
|
||||
|
||||
Bedrock requires all toolResult and toolUse IDs within a single message to
|
||||
be unique. When merging consecutive messages, duplicates can occur if the
|
||||
same tool_call_id appears multiple times in conversation history.
|
||||
|
||||
When duplicates exist, the first occurrence is retained and subsequent ones
|
||||
are discarded. A warning is logged for every dropped block so that
|
||||
upstream duplication bugs remain visible.
|
||||
|
||||
Blocks that do not contain ``block_key`` (e.g., cachePoint, text) are
|
||||
always preserved.
|
||||
|
||||
Args:
|
||||
blocks: The list of Bedrock content blocks to deduplicate.
|
||||
block_key: The dict key to inspect (e.g. ``"toolResult"`` or ``"toolUse"``).
|
||||
id_key: The nested key that holds the unique ID (default ``"toolUseId"``).
|
||||
"""
|
||||
seen_ids: Set[str] = set()
|
||||
deduplicated: List[BedrockContentBlock] = []
|
||||
for block in blocks:
|
||||
keyed = block.get(block_key)
|
||||
if keyed is not None and isinstance(keyed, dict):
|
||||
block_id = keyed.get(id_key)
|
||||
if block_id:
|
||||
if block_id in seen_ids:
|
||||
verbose_logger.warning(
|
||||
"Bedrock Converse: dropping duplicate %s block with "
|
||||
"%s=%s. This may indicate duplicate tool messages in "
|
||||
"conversation history.",
|
||||
block_key,
|
||||
id_key,
|
||||
block_id,
|
||||
)
|
||||
continue
|
||||
seen_ids.add(block_id)
|
||||
deduplicated.append(block)
|
||||
return deduplicated
|
||||
|
||||
|
||||
def _deduplicate_bedrock_tool_content(
|
||||
tool_content: List[BedrockContentBlock],
|
||||
) -> List[BedrockContentBlock]:
|
||||
"""Convenience wrapper: deduplicate ``toolResult`` blocks by ``toolUseId``."""
|
||||
return _deduplicate_bedrock_content_blocks(tool_content, "toolResult")
|
||||
|
||||
|
||||
def _insert_assistant_continue_message(
|
||||
messages: List[BedrockMessageBlock],
|
||||
assistant_continue_message: Optional[
|
||||
|
|
@ -3867,6 +3930,8 @@ class BedrockConverseMessagesProcessor:
|
|||
tool_content.append(cache_point_block)
|
||||
|
||||
msg_i += 1
|
||||
# Deduplicate toolResult blocks with the same toolUseId
|
||||
tool_content = _deduplicate_bedrock_tool_content(tool_content)
|
||||
if tool_content:
|
||||
# if last message was a 'user' message, then add a blank assistant message (bedrock requires alternating roles)
|
||||
if len(contents) > 0 and contents[-1]["role"] == "user":
|
||||
|
|
@ -3932,10 +3997,12 @@ class BedrockConverseMessagesProcessor:
|
|||
assistant_parts=assistants_parts,
|
||||
)
|
||||
elif element["type"] == "text":
|
||||
assistants_part = BedrockContentBlock(
|
||||
text=element["text"]
|
||||
)
|
||||
assistants_parts.append(assistants_part)
|
||||
# Skip completely empty strings to avoid blank content blocks
|
||||
if element.get("text", "").strip():
|
||||
assistants_part = BedrockContentBlock(
|
||||
text=element["text"]
|
||||
)
|
||||
assistants_parts.append(assistants_part)
|
||||
elif element["type"] == "image_url":
|
||||
if isinstance(element["image_url"], dict):
|
||||
image_url = element["image_url"]["url"]
|
||||
|
|
@ -3960,9 +4027,12 @@ class BedrockConverseMessagesProcessor:
|
|||
elif _assistant_content is not None and isinstance(
|
||||
_assistant_content, str
|
||||
):
|
||||
assistant_content.append(
|
||||
BedrockContentBlock(text=_assistant_content)
|
||||
)
|
||||
# Skip completely empty strings to avoid blank content blocks
|
||||
if _assistant_content.strip():
|
||||
assistant_content.append(
|
||||
BedrockContentBlock(text=_assistant_content)
|
||||
)
|
||||
# If content is empty/whitespace, skip it (don't add a placeholder)
|
||||
# Add cache point block for assistant string content
|
||||
_cache_point_block = (
|
||||
litellm.AmazonConverseConfig()._get_cache_point_block(
|
||||
|
|
@ -3980,6 +4050,8 @@ class BedrockConverseMessagesProcessor:
|
|||
|
||||
msg_i += 1
|
||||
|
||||
assistant_content = _deduplicate_bedrock_content_blocks(assistant_content, "toolUse")
|
||||
|
||||
if assistant_content:
|
||||
contents.append(
|
||||
BedrockMessageBlock(role="assistant", content=assistant_content)
|
||||
|
|
@ -4230,6 +4302,8 @@ def _bedrock_converse_messages_pt( # noqa: PLR0915
|
|||
tool_content.append(cache_point_block)
|
||||
|
||||
msg_i += 1
|
||||
# Deduplicate toolResult blocks with the same toolUseId
|
||||
tool_content = _deduplicate_bedrock_tool_content(tool_content)
|
||||
if tool_content:
|
||||
# if last message was a 'user' message, then add a blank assistant message (bedrock requires alternating roles)
|
||||
if len(contents) > 0 and contents[-1]["role"] == "user":
|
||||
|
|
@ -4289,12 +4363,11 @@ def _bedrock_converse_messages_pt( # noqa: PLR0915
|
|||
assistant_parts=assistants_parts,
|
||||
)
|
||||
elif element["type"] == "text":
|
||||
# AWS Bedrock doesn't allow empty or whitespace-only text content, so use placeholder for empty strings
|
||||
text_content = (
|
||||
element["text"] if element["text"].strip() else "."
|
||||
)
|
||||
assistants_part = BedrockContentBlock(text=text_content)
|
||||
assistants_parts.append(assistants_part)
|
||||
# AWS Bedrock doesn't allow empty or whitespace-only text content
|
||||
# Skip completely empty strings to avoid blank content blocks
|
||||
if element.get("text", "").strip():
|
||||
assistants_part = BedrockContentBlock(text=element["text"])
|
||||
assistants_parts.append(assistants_part)
|
||||
elif element["type"] == "image_url":
|
||||
if isinstance(element["image_url"], dict):
|
||||
image_url = element["image_url"]["url"]
|
||||
|
|
@ -4317,9 +4390,9 @@ def _bedrock_converse_messages_pt( # noqa: PLR0915
|
|||
assistants_parts.append(_cache_point_block)
|
||||
assistant_content.extend(assistants_parts)
|
||||
elif _assistant_content is not None and isinstance(_assistant_content, str):
|
||||
# AWS Bedrock doesn't allow empty or whitespace-only text content, so use placeholder for empty strings
|
||||
text_content = _assistant_content if _assistant_content.strip() else "."
|
||||
assistant_content.append(BedrockContentBlock(text=text_content))
|
||||
# Skip completely empty strings to avoid blank content blocks
|
||||
if _assistant_content.strip():
|
||||
assistant_content.append(BedrockContentBlock(text=_assistant_content))
|
||||
# Add cache point block for assistant string content
|
||||
_cache_point_block = (
|
||||
litellm.AmazonConverseConfig()._get_cache_point_block(
|
||||
|
|
@ -4336,6 +4409,8 @@ def _bedrock_converse_messages_pt( # noqa: PLR0915
|
|||
|
||||
msg_i += 1
|
||||
|
||||
assistant_content = _deduplicate_bedrock_content_blocks(assistant_content, "toolUse")
|
||||
|
||||
if assistant_content:
|
||||
contents.append(
|
||||
BedrockMessageBlock(role="assistant", content=assistant_content)
|
||||
|
|
|
|||
|
|
@ -130,6 +130,11 @@ def perform_redaction(model_call_details: dict, result):
|
|||
def should_redact_message_logging(model_call_details: dict) -> bool:
|
||||
"""
|
||||
Determine if message logging should be redacted.
|
||||
|
||||
Priority order:
|
||||
1. Dynamic parameter (turn_off_message_logging in request)
|
||||
2. Headers (litellm-disable-message-redaction / litellm-enable-message-redaction)
|
||||
3. Global setting (litellm.turn_off_message_logging)
|
||||
"""
|
||||
litellm_params = model_call_details.get("litellm_params", {})
|
||||
|
||||
|
|
@ -139,36 +144,36 @@ def should_redact_message_logging(model_call_details: dict) -> bool:
|
|||
# Get headers from the metadata
|
||||
request_headers = metadata.get("headers", {}) if isinstance(metadata, dict) else {}
|
||||
|
||||
possible_request_headers = [
|
||||
# Check for headers that explicitly control redaction
|
||||
if request_headers and bool(
|
||||
request_headers.get("litellm-disable-message-redaction", False)
|
||||
):
|
||||
# User explicitly disabled redaction via header
|
||||
return False
|
||||
|
||||
possible_enable_headers = [
|
||||
"litellm-enable-message-redaction", # old header. maintain backwards compatibility
|
||||
"x-litellm-enable-message-redaction", # new header
|
||||
]
|
||||
|
||||
is_redaction_enabled_via_header = False
|
||||
for header in possible_request_headers:
|
||||
for header in possible_enable_headers:
|
||||
if bool(request_headers.get(header, False)):
|
||||
is_redaction_enabled_via_header = True
|
||||
break
|
||||
|
||||
# check if user opted out of logging message/response to callbacks
|
||||
if (
|
||||
litellm.turn_off_message_logging is not True
|
||||
and is_redaction_enabled_via_header is not True
|
||||
and _get_turn_off_message_logging_from_dynamic_params(model_call_details)
|
||||
is not True
|
||||
):
|
||||
return False
|
||||
|
||||
if request_headers and bool(
|
||||
request_headers.get("litellm-disable-message-redaction", False)
|
||||
):
|
||||
return False
|
||||
|
||||
# user has OPTED OUT of message redaction
|
||||
if _get_turn_off_message_logging_from_dynamic_params(model_call_details) is False:
|
||||
return False
|
||||
|
||||
return True
|
||||
# Priority 1: Check dynamic parameter first (if explicitly set)
|
||||
dynamic_turn_off = _get_turn_off_message_logging_from_dynamic_params(model_call_details)
|
||||
if dynamic_turn_off is not None:
|
||||
# Dynamic parameter is explicitly set, use it
|
||||
return dynamic_turn_off
|
||||
|
||||
# Priority 2: Check if header explicitly enables redaction
|
||||
if is_redaction_enabled_via_header:
|
||||
return True
|
||||
|
||||
# Priority 3: Fall back to global setting
|
||||
return litellm.turn_off_message_logging is True
|
||||
|
||||
|
||||
def redact_message_input_output_from_logging(
|
||||
|
|
|
|||
6
litellm/llms/a2a/__init__.py
Normal file
6
litellm/llms/a2a/__init__.py
Normal file
|
|
@ -0,0 +1,6 @@
|
|||
"""
|
||||
A2A (Agent-to-Agent) Protocol Provider for LiteLLM
|
||||
"""
|
||||
from .chat.transformation import A2AConfig
|
||||
|
||||
__all__ = ["A2AConfig"]
|
||||
6
litellm/llms/a2a/chat/__init__.py
Normal file
6
litellm/llms/a2a/chat/__init__.py
Normal file
|
|
@ -0,0 +1,6 @@
|
|||
"""
|
||||
A2A Chat Completion Implementation
|
||||
"""
|
||||
from .transformation import A2AConfig
|
||||
|
||||
__all__ = ["A2AConfig"]
|
||||
103
litellm/llms/a2a/chat/streaming_iterator.py
Normal file
103
litellm/llms/a2a/chat/streaming_iterator.py
Normal file
|
|
@ -0,0 +1,103 @@
|
|||
"""
|
||||
A2A Streaming Response Iterator
|
||||
"""
|
||||
from typing import Optional, Union
|
||||
|
||||
from litellm.llms.base_llm.base_model_iterator import BaseModelResponseIterator
|
||||
from litellm.types.utils import GenericStreamingChunk, ModelResponseStream
|
||||
|
||||
from ..common_utils import extract_text_from_a2a_response
|
||||
|
||||
|
||||
class A2AModelResponseIterator(BaseModelResponseIterator):
|
||||
"""
|
||||
Iterator for parsing A2A streaming responses.
|
||||
|
||||
Converts A2A JSON-RPC streaming chunks to OpenAI-compatible format.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
streaming_response,
|
||||
sync_stream: bool,
|
||||
json_mode: Optional[bool] = False,
|
||||
model: str = "a2a/agent",
|
||||
):
|
||||
super().__init__(
|
||||
streaming_response=streaming_response,
|
||||
sync_stream=sync_stream,
|
||||
json_mode=json_mode,
|
||||
)
|
||||
self.model = model
|
||||
|
||||
def chunk_parser(self, chunk: dict) -> Union[GenericStreamingChunk, ModelResponseStream]:
|
||||
"""
|
||||
Parse A2A streaming chunk to OpenAI format.
|
||||
|
||||
A2A chunk format:
|
||||
{
|
||||
"jsonrpc": "2.0",
|
||||
"id": "request-id",
|
||||
"result": {
|
||||
"message": {
|
||||
"parts": [{"kind": "text", "text": "content"}]
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
Or for tasks:
|
||||
{
|
||||
"jsonrpc": "2.0",
|
||||
"result": {
|
||||
"kind": "task",
|
||||
"status": {"state": "running"},
|
||||
"artifacts": [{"parts": [{"kind": "text", "text": "content"}]}]
|
||||
}
|
||||
}
|
||||
"""
|
||||
try:
|
||||
# Extract text from A2A response
|
||||
text = extract_text_from_a2a_response(chunk)
|
||||
|
||||
# Determine finish reason
|
||||
finish_reason = self._get_finish_reason(chunk)
|
||||
|
||||
# Return generic streaming chunk
|
||||
return GenericStreamingChunk(
|
||||
text=text,
|
||||
is_finished=bool(finish_reason),
|
||||
finish_reason=finish_reason or "",
|
||||
usage=None,
|
||||
index=0,
|
||||
tool_use=None,
|
||||
)
|
||||
except Exception:
|
||||
# Return empty chunk on parse error
|
||||
return GenericStreamingChunk(
|
||||
text="",
|
||||
is_finished=False,
|
||||
finish_reason="",
|
||||
usage=None,
|
||||
index=0,
|
||||
tool_use=None,
|
||||
)
|
||||
|
||||
def _get_finish_reason(self, chunk: dict) -> Optional[str]:
|
||||
"""Extract finish reason from A2A chunk"""
|
||||
result = chunk.get("result", {})
|
||||
|
||||
# Check for task completion
|
||||
if isinstance(result, dict):
|
||||
status = result.get("status", {})
|
||||
if isinstance(status, dict):
|
||||
state = status.get("state")
|
||||
if state == "completed":
|
||||
return "stop"
|
||||
elif state == "failed":
|
||||
return "stop" # Map failed state to 'stop' (valid finish_reason)
|
||||
|
||||
# Check for [DONE] marker
|
||||
if chunk.get("done") is True:
|
||||
return "stop"
|
||||
|
||||
return None
|
||||
370
litellm/llms/a2a/chat/transformation.py
Normal file
370
litellm/llms/a2a/chat/transformation.py
Normal file
|
|
@ -0,0 +1,370 @@
|
|||
"""
|
||||
A2A Protocol Transformation for LiteLLM
|
||||
"""
|
||||
import uuid
|
||||
from typing import Any, Dict, Iterator, List, Optional, Union
|
||||
|
||||
import httpx
|
||||
|
||||
from litellm.llms.base_llm.base_model_iterator import BaseModelResponseIterator
|
||||
from litellm.llms.base_llm.chat.transformation import BaseConfig, BaseLLMException
|
||||
from litellm.types.llms.openai import AllMessageValues
|
||||
from litellm.types.utils import Choices, Message, ModelResponse
|
||||
|
||||
from ..common_utils import (
|
||||
A2AError,
|
||||
convert_messages_to_prompt,
|
||||
extract_text_from_a2a_response,
|
||||
)
|
||||
from .streaming_iterator import A2AModelResponseIterator
|
||||
|
||||
|
||||
class A2AConfig(BaseConfig):
|
||||
"""
|
||||
Configuration for A2A (Agent-to-Agent) Protocol.
|
||||
|
||||
Handles transformation between OpenAI and A2A JSON-RPC 2.0 formats.
|
||||
"""
|
||||
|
||||
@staticmethod
|
||||
def resolve_agent_config_from_registry(
|
||||
model: str,
|
||||
api_base: Optional[str],
|
||||
api_key: Optional[str],
|
||||
headers: Optional[Dict[str, Any]],
|
||||
optional_params: Dict[str, Any],
|
||||
) -> tuple[Optional[str], Optional[str], Optional[Dict[str, Any]]]:
|
||||
"""
|
||||
Resolve agent configuration from registry if model format is "a2a/<agent-name>".
|
||||
|
||||
Extracts agent name from model string and looks up configuration in the
|
||||
agent registry (if available in proxy context).
|
||||
|
||||
Args:
|
||||
model: Model string (e.g., "a2a/my-agent")
|
||||
api_base: Explicit api_base (takes precedence over registry)
|
||||
api_key: Explicit api_key (takes precedence over registry)
|
||||
headers: Explicit headers (takes precedence over registry)
|
||||
optional_params: Dict to merge additional litellm_params into
|
||||
|
||||
Returns:
|
||||
Tuple of (api_base, api_key, headers) with registry values filled in
|
||||
"""
|
||||
# Extract agent name from model (e.g., "a2a/my-agent" -> "my-agent")
|
||||
agent_name = model.split("/", 1)[1] if "/" in model else None
|
||||
|
||||
# Only lookup if agent name exists and some config is missing
|
||||
if not agent_name or (api_base is not None and api_key is not None and headers is not None):
|
||||
return api_base, api_key, headers
|
||||
|
||||
# Try registry lookup (only available in proxy context)
|
||||
try:
|
||||
from litellm.proxy.agent_endpoints.agent_registry import (
|
||||
global_agent_registry,
|
||||
)
|
||||
|
||||
agent = global_agent_registry.get_agent_by_name(agent_name)
|
||||
if agent:
|
||||
# Get api_base from agent card URL
|
||||
if api_base is None and agent.agent_card_params:
|
||||
api_base = agent.agent_card_params.get("url")
|
||||
|
||||
# Get api_key, headers, and other params from litellm_params
|
||||
if agent.litellm_params:
|
||||
if api_key is None:
|
||||
api_key = agent.litellm_params.get("api_key")
|
||||
|
||||
if headers is None:
|
||||
agent_headers = agent.litellm_params.get("headers")
|
||||
if agent_headers:
|
||||
headers = agent_headers
|
||||
|
||||
# Merge other litellm_params (timeout, max_retries, etc.)
|
||||
for key, value in agent.litellm_params.items():
|
||||
if key not in ["api_key", "api_base", "headers", "model"] and key not in optional_params:
|
||||
optional_params[key] = value
|
||||
except ImportError:
|
||||
pass # Registry not available (not running in proxy context)
|
||||
|
||||
return api_base, api_key, headers
|
||||
|
||||
def get_supported_openai_params(self, model: str) -> List[str]:
|
||||
"""Return list of supported OpenAI parameters"""
|
||||
return [
|
||||
"stream",
|
||||
"temperature",
|
||||
"max_tokens",
|
||||
"top_p",
|
||||
]
|
||||
|
||||
def map_openai_params(
|
||||
self,
|
||||
non_default_params: dict,
|
||||
optional_params: dict,
|
||||
model: str,
|
||||
drop_params: bool,
|
||||
) -> dict:
|
||||
"""
|
||||
Map OpenAI parameters to A2A parameters.
|
||||
|
||||
For A2A protocol, we need to map the stream parameter so
|
||||
transform_request can determine which JSON-RPC method to use.
|
||||
"""
|
||||
# Map stream parameter
|
||||
for param, value in non_default_params.items():
|
||||
if param == "stream" and value is True:
|
||||
optional_params["stream"] = value
|
||||
|
||||
return optional_params
|
||||
|
||||
def validate_environment(
|
||||
self,
|
||||
headers: dict,
|
||||
model: str,
|
||||
messages: List[AllMessageValues],
|
||||
optional_params: dict,
|
||||
litellm_params: dict,
|
||||
api_key: Optional[str] = None,
|
||||
api_base: Optional[str] = None,
|
||||
) -> dict:
|
||||
"""
|
||||
Validate environment and set headers for A2A requests.
|
||||
|
||||
Args:
|
||||
headers: Request headers dict
|
||||
model: Model name
|
||||
messages: Messages list
|
||||
optional_params: Optional parameters
|
||||
litellm_params: LiteLLM parameters
|
||||
api_key: API key (optional for A2A)
|
||||
api_base: API base URL
|
||||
|
||||
Returns:
|
||||
Updated headers dict
|
||||
"""
|
||||
# Ensure Content-Type is set to application/json for JSON-RPC 2.0
|
||||
if "content-type" not in headers and "Content-Type" not in headers:
|
||||
headers["Content-Type"] = "application/json"
|
||||
|
||||
# Add Authorization header if API key is provided
|
||||
if api_key is not None:
|
||||
headers["Authorization"] = f"Bearer {api_key}"
|
||||
|
||||
return headers
|
||||
|
||||
def get_complete_url(
|
||||
self,
|
||||
api_base: Optional[str],
|
||||
api_key: Optional[str],
|
||||
model: str,
|
||||
optional_params: dict,
|
||||
litellm_params: dict,
|
||||
stream: Optional[bool] = None,
|
||||
) -> str:
|
||||
"""
|
||||
Get the complete A2A agent endpoint URL.
|
||||
|
||||
A2A agents use JSON-RPC 2.0 at the base URL, not specific paths.
|
||||
The method (message/send or message/stream) is specified in the
|
||||
JSON-RPC request body, not in the URL.
|
||||
|
||||
Args:
|
||||
api_base: Base URL of the A2A agent (e.g., "http://0.0.0.0:9999")
|
||||
api_key: API key (not used for URL construction)
|
||||
model: Model name (not used for A2A, agent determined by api_base)
|
||||
optional_params: Optional parameters
|
||||
litellm_params: LiteLLM parameters
|
||||
stream: Whether this is a streaming request (affects JSON-RPC method)
|
||||
|
||||
Returns:
|
||||
Complete URL for the A2A endpoint (base URL)
|
||||
"""
|
||||
if api_base is None:
|
||||
raise ValueError("api_base is required for A2A provider")
|
||||
|
||||
# A2A uses JSON-RPC 2.0 at the base URL
|
||||
# Remove trailing slash for consistency
|
||||
return api_base.rstrip("/")
|
||||
|
||||
def transform_request(
|
||||
self,
|
||||
model: str,
|
||||
messages: List[AllMessageValues],
|
||||
optional_params: dict,
|
||||
litellm_params: dict,
|
||||
headers: dict,
|
||||
) -> dict:
|
||||
"""
|
||||
Transform OpenAI request to A2A JSON-RPC 2.0 format.
|
||||
|
||||
Args:
|
||||
model: Model name
|
||||
messages: List of OpenAI messages
|
||||
optional_params: Optional parameters
|
||||
litellm_params: LiteLLM parameters
|
||||
headers: Request headers
|
||||
|
||||
Returns:
|
||||
A2A JSON-RPC 2.0 request dict
|
||||
"""
|
||||
# Generate request ID
|
||||
request_id = str(uuid.uuid4())
|
||||
|
||||
if not messages:
|
||||
raise ValueError("At least one message is required for A2A completion")
|
||||
|
||||
# Convert all messages to maintain conversation history
|
||||
# Use helper to format conversation with role prefixes
|
||||
full_context = convert_messages_to_prompt(messages)
|
||||
|
||||
# Create single A2A message with full conversation context
|
||||
a2a_message = {
|
||||
"role": "user",
|
||||
"parts": [{"kind": "text", "text": full_context}],
|
||||
"messageId": str(uuid.uuid4()),
|
||||
}
|
||||
|
||||
# Build JSON-RPC 2.0 request
|
||||
# For A2A protocol, the method is "message/send" for non-streaming
|
||||
# and "message/stream" for streaming
|
||||
stream = optional_params.get("stream", False)
|
||||
method = "message/stream" if stream else "message/send"
|
||||
|
||||
request_data = {
|
||||
"jsonrpc": "2.0",
|
||||
"id": request_id,
|
||||
"method": method,
|
||||
"params": {
|
||||
"message": a2a_message
|
||||
}
|
||||
}
|
||||
|
||||
return request_data
|
||||
|
||||
def transform_response(
|
||||
self,
|
||||
model: str,
|
||||
raw_response: httpx.Response,
|
||||
model_response: ModelResponse,
|
||||
logging_obj: Any,
|
||||
request_data: dict,
|
||||
messages: List[AllMessageValues],
|
||||
optional_params: dict,
|
||||
litellm_params: dict,
|
||||
encoding: Any,
|
||||
api_key: Optional[str] = None,
|
||||
json_mode: Optional[bool] = None,
|
||||
) -> ModelResponse:
|
||||
"""
|
||||
Transform A2A JSON-RPC 2.0 response to OpenAI format.
|
||||
|
||||
Args:
|
||||
model: Model name
|
||||
raw_response: HTTP response from A2A agent
|
||||
model_response: Model response object to populate
|
||||
logging_obj: Logging object
|
||||
request_data: Original request data
|
||||
messages: Original messages
|
||||
optional_params: Optional parameters
|
||||
litellm_params: LiteLLM parameters
|
||||
encoding: Encoding object
|
||||
api_key: API key
|
||||
json_mode: JSON mode flag
|
||||
|
||||
Returns:
|
||||
Populated ModelResponse object
|
||||
"""
|
||||
try:
|
||||
response_json = raw_response.json()
|
||||
except Exception as e:
|
||||
raise A2AError(
|
||||
status_code=raw_response.status_code,
|
||||
message=f"Failed to parse A2A response: {str(e)}",
|
||||
headers=dict(raw_response.headers),
|
||||
)
|
||||
|
||||
# Check for JSON-RPC error
|
||||
if "error" in response_json:
|
||||
error = response_json["error"]
|
||||
raise A2AError(
|
||||
status_code=raw_response.status_code,
|
||||
message=f"A2A error: {error.get('message', 'Unknown error')}",
|
||||
headers=dict(raw_response.headers),
|
||||
)
|
||||
|
||||
# Extract text from A2A response
|
||||
text = extract_text_from_a2a_response(response_json)
|
||||
|
||||
# Populate model response
|
||||
model_response.choices = [
|
||||
Choices(
|
||||
finish_reason="stop",
|
||||
index=0,
|
||||
message=Message(
|
||||
content=text,
|
||||
role="assistant",
|
||||
),
|
||||
)
|
||||
]
|
||||
|
||||
# Set model
|
||||
model_response.model = model
|
||||
|
||||
# Set ID from response
|
||||
model_response.id = response_json.get("id", str(uuid.uuid4()))
|
||||
|
||||
return model_response
|
||||
|
||||
def get_model_response_iterator(
|
||||
self,
|
||||
streaming_response: Union[Iterator, Any],
|
||||
sync_stream: bool,
|
||||
json_mode: Optional[bool] = False,
|
||||
) -> BaseModelResponseIterator:
|
||||
"""
|
||||
Get streaming iterator for A2A responses.
|
||||
|
||||
Args:
|
||||
streaming_response: Streaming response iterator
|
||||
sync_stream: Whether this is a sync stream
|
||||
json_mode: JSON mode flag
|
||||
|
||||
Returns:
|
||||
A2A streaming iterator
|
||||
"""
|
||||
return A2AModelResponseIterator(
|
||||
streaming_response=streaming_response,
|
||||
sync_stream=sync_stream,
|
||||
json_mode=json_mode,
|
||||
)
|
||||
|
||||
def _openai_message_to_a2a_message(self, message: Dict[str, Any]) -> Dict[str, Any]:
|
||||
"""
|
||||
Convert OpenAI message to A2A message format.
|
||||
|
||||
Args:
|
||||
message: OpenAI message dict
|
||||
|
||||
Returns:
|
||||
A2A message dict
|
||||
"""
|
||||
content = message.get("content", "")
|
||||
role = message.get("role", "user")
|
||||
|
||||
return {
|
||||
"role": role,
|
||||
"parts": [{"kind": "text", "text": str(content)}],
|
||||
"messageId": str(uuid.uuid4()),
|
||||
}
|
||||
|
||||
def get_error_class(
|
||||
self, error_message: str, status_code: int, headers: Union[dict, httpx.Headers]
|
||||
) -> BaseLLMException:
|
||||
"""Return appropriate error class for A2A errors"""
|
||||
# Convert headers to dict if needed
|
||||
headers_dict = dict(headers) if isinstance(headers, httpx.Headers) else headers
|
||||
return A2AError(
|
||||
status_code=status_code,
|
||||
message=error_message,
|
||||
headers=headers_dict,
|
||||
)
|
||||
152
litellm/llms/a2a/common_utils.py
Normal file
152
litellm/llms/a2a/common_utils.py
Normal file
|
|
@ -0,0 +1,152 @@
|
|||
"""
|
||||
Common utilities for A2A (Agent-to-Agent) Protocol
|
||||
"""
|
||||
from typing import Any, Dict, List
|
||||
|
||||
from pydantic import BaseModel
|
||||
|
||||
from litellm.litellm_core_utils.prompt_templates.common_utils import (
|
||||
convert_content_list_to_str,
|
||||
)
|
||||
from litellm.llms.base_llm.chat.transformation import BaseLLMException
|
||||
from litellm.types.llms.openai import AllMessageValues
|
||||
|
||||
|
||||
class A2AError(BaseLLMException):
|
||||
"""Base exception for A2A protocol errors"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
status_code: int,
|
||||
message: str,
|
||||
headers: Dict[str, Any] = {},
|
||||
):
|
||||
super().__init__(
|
||||
status_code=status_code,
|
||||
message=message,
|
||||
headers=headers,
|
||||
)
|
||||
|
||||
|
||||
def convert_messages_to_prompt(messages: List[AllMessageValues]) -> str:
|
||||
"""
|
||||
Convert OpenAI messages to a single prompt string for A2A agent.
|
||||
|
||||
Formats each message as "{role}: {content}" and joins with newlines
|
||||
to preserve conversation history. Handles both string and list content.
|
||||
|
||||
Args:
|
||||
messages: List of OpenAI-format messages
|
||||
|
||||
Returns:
|
||||
Formatted prompt string with full conversation context
|
||||
"""
|
||||
conversation_parts = []
|
||||
for msg in messages:
|
||||
# Use LiteLLM's helper to extract text from content (handles both str and list)
|
||||
content_text = convert_content_list_to_str(message=msg)
|
||||
|
||||
# Get role
|
||||
if isinstance(msg, BaseModel):
|
||||
role = msg.model_dump().get("role", "user")
|
||||
elif isinstance(msg, dict):
|
||||
role = msg.get("role", "user")
|
||||
else:
|
||||
role = dict(msg).get("role", "user") # type: ignore
|
||||
|
||||
if content_text:
|
||||
conversation_parts.append(f"{role}: {content_text}")
|
||||
|
||||
return "\n".join(conversation_parts)
|
||||
|
||||
|
||||
def extract_text_from_a2a_message(
|
||||
message: Dict[str, Any], depth: int = 0, max_depth: int = 10
|
||||
) -> str:
|
||||
"""
|
||||
Extract text content from A2A message parts.
|
||||
|
||||
Args:
|
||||
message: A2A message dict with 'parts' containing text parts
|
||||
depth: Current recursion depth (internal use)
|
||||
max_depth: Maximum recursion depth to prevent infinite loops
|
||||
|
||||
Returns:
|
||||
Concatenated text from all text parts
|
||||
"""
|
||||
if message is None or depth >= max_depth:
|
||||
return ""
|
||||
|
||||
parts = message.get("parts", [])
|
||||
text_parts: List[str] = []
|
||||
|
||||
for part in parts:
|
||||
if part.get("kind") == "text":
|
||||
text_parts.append(part.get("text", ""))
|
||||
# Handle nested parts if they exist
|
||||
elif "parts" in part:
|
||||
nested_text = extract_text_from_a2a_message(part, depth + 1, max_depth)
|
||||
if nested_text:
|
||||
text_parts.append(nested_text)
|
||||
|
||||
return " ".join(text_parts)
|
||||
|
||||
|
||||
def extract_text_from_a2a_response(
|
||||
response_dict: Dict[str, Any], max_depth: int = 10
|
||||
) -> str:
|
||||
"""
|
||||
Extract text content from A2A response result.
|
||||
|
||||
Args:
|
||||
response_dict: A2A response dict with 'result' containing message
|
||||
max_depth: Maximum recursion depth to prevent infinite loops
|
||||
|
||||
Returns:
|
||||
Text from response message parts
|
||||
"""
|
||||
result = response_dict.get("result", {})
|
||||
if not isinstance(result, dict):
|
||||
return ""
|
||||
|
||||
# A2A response can have different formats:
|
||||
# 1. Direct message: {"result": {"kind": "message", "parts": [...]}}
|
||||
# 2. Nested message: {"result": {"message": {"parts": [...]}}}
|
||||
# 3. Task with artifacts: {"result": {"kind": "task", "artifacts": [{"parts": [...]}]}}
|
||||
# 4. Task with status message: {"result": {"kind": "task", "status": {"message": {"parts": [...]}}}}
|
||||
# 5. Streaming artifact-update: {"result": {"kind": "artifact-update", "artifact": {"parts": [...]}}}
|
||||
|
||||
# Check if result itself has parts (direct message)
|
||||
if "parts" in result:
|
||||
return extract_text_from_a2a_message(result, depth=0, max_depth=max_depth)
|
||||
|
||||
# Check for nested message
|
||||
message = result.get("message")
|
||||
if message:
|
||||
return extract_text_from_a2a_message(message, depth=0, max_depth=max_depth)
|
||||
|
||||
# Check for streaming artifact-update (singular artifact)
|
||||
artifact = result.get("artifact")
|
||||
if artifact and isinstance(artifact, dict):
|
||||
return extract_text_from_a2a_message(
|
||||
artifact, depth=0, max_depth=max_depth
|
||||
)
|
||||
|
||||
# Check for task status message (common in Gemini A2A agents)
|
||||
status = result.get("status", {})
|
||||
if isinstance(status, dict):
|
||||
status_message = status.get("message")
|
||||
if status_message:
|
||||
return extract_text_from_a2a_message(
|
||||
status_message, depth=0, max_depth=max_depth
|
||||
)
|
||||
|
||||
# Handle task result with artifacts (plural, array)
|
||||
artifacts = result.get("artifacts", [])
|
||||
if artifacts and len(artifacts) > 0:
|
||||
first_artifact = artifacts[0]
|
||||
return extract_text_from_a2a_message(
|
||||
first_artifact, depth=0, max_depth=max_depth
|
||||
)
|
||||
|
||||
return ""
|
||||
|
|
@ -34,6 +34,7 @@ from litellm.types.llms.openai import (
|
|||
)
|
||||
from litellm.types.utils import (
|
||||
ChatCompletionMessageToolCall,
|
||||
Choices,
|
||||
GenericGuardrailAPIInputs,
|
||||
ModelResponse,
|
||||
)
|
||||
|
|
@ -74,9 +75,10 @@ class AnthropicMessagesHandler(BaseTranslation):
|
|||
if messages is None:
|
||||
return data
|
||||
|
||||
chat_completion_compatible_request = (
|
||||
chat_completion_compatible_request, tool_name_mapping = (
|
||||
LiteLLMAnthropicMessagesAdapter().translate_anthropic_to_openai(
|
||||
anthropic_message_request=cast(AnthropicMessagesRequest, data)
|
||||
# Use a shallow copy to avoid mutating request data (pop on litellm_metadata).
|
||||
anthropic_message_request=cast(AnthropicMessagesRequest, data.copy())
|
||||
)
|
||||
)
|
||||
|
||||
|
|
@ -84,9 +86,9 @@ class AnthropicMessagesHandler(BaseTranslation):
|
|||
|
||||
texts_to_check: List[str] = []
|
||||
images_to_check: List[str] = []
|
||||
tools_to_check: List[ChatCompletionToolParam] = (
|
||||
chat_completion_compatible_request.get("tools", [])
|
||||
)
|
||||
tools_to_check: List[
|
||||
ChatCompletionToolParam
|
||||
] = chat_completion_compatible_request.get("tools", [])
|
||||
task_mappings: List[Tuple[int, Optional[int]]] = []
|
||||
# Track (message_index, content_index) for each text
|
||||
# content_index is None for string content, int for list content
|
||||
|
|
@ -282,7 +284,10 @@ class AnthropicMessagesHandler(BaseTranslation):
|
|||
if hasattr(content_block, "model_dump"):
|
||||
block_dict = content_block.model_dump()
|
||||
else:
|
||||
block_dict = {"type": block_type, "text": getattr(content_block, "text", None)}
|
||||
block_dict = {
|
||||
"type": block_type,
|
||||
"text": getattr(content_block, "text", None),
|
||||
}
|
||||
else:
|
||||
continue
|
||||
|
||||
|
|
@ -358,30 +363,40 @@ class AnthropicMessagesHandler(BaseTranslation):
|
|||
"""
|
||||
has_ended = self._check_streaming_has_ended(responses_so_far)
|
||||
if has_ended:
|
||||
|
||||
# build the model response from the responses_so_far
|
||||
model_response = cast(
|
||||
ModelResponse,
|
||||
AnthropicPassthroughLoggingHandler._build_complete_streaming_response(
|
||||
all_chunks=responses_so_far,
|
||||
litellm_logging_obj=cast("LiteLLMLoggingObj", litellm_logging_obj),
|
||||
model="",
|
||||
),
|
||||
built_response = AnthropicPassthroughLoggingHandler._build_complete_streaming_response(
|
||||
all_chunks=responses_so_far,
|
||||
litellm_logging_obj=cast("LiteLLMLoggingObj", litellm_logging_obj),
|
||||
model="",
|
||||
)
|
||||
tool_calls_list = cast(Optional[List[ChatCompletionMessageToolCall]], model_response.choices[0].message.tool_calls) # type: ignore
|
||||
string_so_far = model_response.choices[0].message.content # type: ignore
|
||||
guardrail_inputs = GenericGuardrailAPIInputs()
|
||||
if string_so_far:
|
||||
guardrail_inputs["texts"] = [string_so_far]
|
||||
if tool_calls_list:
|
||||
guardrail_inputs["tool_calls"] = tool_calls_list
|
||||
|
||||
_guardrailed_inputs = await guardrail_to_apply.apply_guardrail( # allow rejecting the response, if invalid
|
||||
inputs=guardrail_inputs,
|
||||
request_data={},
|
||||
input_type="response",
|
||||
logging_obj=litellm_logging_obj,
|
||||
)
|
||||
# Check if model_response is valid and has choices before accessing
|
||||
if (
|
||||
built_response is not None
|
||||
and hasattr(built_response, "choices")
|
||||
and built_response.choices
|
||||
):
|
||||
model_response = cast(ModelResponse, built_response)
|
||||
first_choice = cast(Choices, model_response.choices[0])
|
||||
tool_calls_list = cast(
|
||||
Optional[List[ChatCompletionMessageToolCall]],
|
||||
first_choice.message.tool_calls,
|
||||
)
|
||||
string_so_far = first_choice.message.content
|
||||
guardrail_inputs = GenericGuardrailAPIInputs()
|
||||
if string_so_far:
|
||||
guardrail_inputs["texts"] = [string_so_far]
|
||||
if tool_calls_list:
|
||||
guardrail_inputs["tool_calls"] = tool_calls_list
|
||||
|
||||
_guardrailed_inputs = await guardrail_to_apply.apply_guardrail( # allow rejecting the response, if invalid
|
||||
inputs=guardrail_inputs,
|
||||
request_data={},
|
||||
input_type="response",
|
||||
logging_obj=litellm_logging_obj,
|
||||
)
|
||||
else:
|
||||
verbose_proxy_logger.debug("Skipping output guardrail - model response has no choices")
|
||||
return responses_so_far
|
||||
|
||||
string_so_far = self.get_streaming_string_so_far(responses_so_far)
|
||||
|
|
@ -648,7 +663,10 @@ class AnthropicMessagesHandler(BaseTranslation):
|
|||
if isinstance(content_block, dict):
|
||||
if content_block.get("type") == "text":
|
||||
cast(Dict[str, Any], content_block)["text"] = guardrail_response
|
||||
elif hasattr(content_block, "type") and getattr(content_block, "type", None) == "text":
|
||||
elif (
|
||||
hasattr(content_block, "type")
|
||||
and getattr(content_block, "type", None) == "text"
|
||||
):
|
||||
# Update Pydantic object's text attribute
|
||||
if hasattr(content_block, "text"):
|
||||
content_block.text = guardrail_response
|
||||
|
|
|
|||
|
|
@ -512,6 +512,9 @@ class ModelResponseIterator:
|
|||
# Accumulate web_search_tool_result blocks for multi-turn reconstruction
|
||||
# See: https://github.com/BerriAI/litellm/issues/17737
|
||||
self.web_search_results: List[Dict[str, Any]] = []
|
||||
|
||||
# Accumulate compaction blocks for multi-turn reconstruction
|
||||
self.compaction_blocks: List[Dict[str, Any]] = []
|
||||
|
||||
def check_empty_tool_call_args(self) -> bool:
|
||||
"""
|
||||
|
|
@ -592,6 +595,12 @@ class ModelResponseIterator:
|
|||
)
|
||||
]
|
||||
provider_specific_fields["thinking_blocks"] = thinking_blocks
|
||||
elif "content" in content_block["delta"] and content_block["delta"].get("type") == "compaction_delta":
|
||||
# Handle compaction delta
|
||||
provider_specific_fields["compaction_delta"] = {
|
||||
"type": "compaction_delta",
|
||||
"content": content_block["delta"]["content"]
|
||||
}
|
||||
|
||||
return text, tool_use, thinking_blocks, provider_specific_fields
|
||||
|
||||
|
|
@ -721,6 +730,20 @@ class ModelResponseIterator:
|
|||
provider_specific_fields=provider_specific_fields,
|
||||
)
|
||||
|
||||
elif content_block_start["content_block"]["type"] == "compaction":
|
||||
# Handle compaction blocks
|
||||
# The full content comes in content_block_start
|
||||
self.compaction_blocks.append(
|
||||
content_block_start["content_block"]
|
||||
)
|
||||
provider_specific_fields["compaction_blocks"] = (
|
||||
self.compaction_blocks
|
||||
)
|
||||
provider_specific_fields["compaction_start"] = {
|
||||
"type": "compaction",
|
||||
"content": content_block_start["content_block"].get("content", "")
|
||||
}
|
||||
|
||||
elif content_block_start["content_block"]["type"].endswith("_tool_result"):
|
||||
# Handle all tool result types (web_search, bash_code_execution, text_editor, etc.)
|
||||
content_type = content_block_start["content_block"]["type"]
|
||||
|
|
|
|||
|
|
@ -170,9 +170,10 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
tool_call["caller"] = cast(Dict[str, Any], anthropic_tool_content["caller"]) # type: ignore[typeddict-item]
|
||||
return tool_call
|
||||
|
||||
def _is_claude_opus_4_5(self, model: str) -> bool:
|
||||
@staticmethod
|
||||
def _is_claude_opus_4_6(model: str) -> bool:
|
||||
"""Check if the model is Claude Opus 4.5."""
|
||||
return "opus-4-5" in model.lower() or "opus_4_5" in model.lower()
|
||||
return "opus-4-6" in model.lower() or "opus_4_6" in model.lower()
|
||||
|
||||
def get_supported_openai_params(self, model: str):
|
||||
params = [
|
||||
|
|
@ -659,32 +660,38 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
|
||||
@staticmethod
|
||||
def _map_reasoning_effort(
|
||||
reasoning_effort: Optional[Union[REASONING_EFFORT, str]],
|
||||
reasoning_effort: Optional[Union[REASONING_EFFORT, str]],
|
||||
model: str,
|
||||
) -> Optional[AnthropicThinkingParam]:
|
||||
if reasoning_effort is None:
|
||||
return None
|
||||
elif reasoning_effort == "low":
|
||||
if AnthropicConfig._is_claude_opus_4_6(model):
|
||||
return AnthropicThinkingParam(
|
||||
type="enabled",
|
||||
budget_tokens=DEFAULT_REASONING_EFFORT_LOW_THINKING_BUDGET,
|
||||
)
|
||||
elif reasoning_effort == "medium":
|
||||
return AnthropicThinkingParam(
|
||||
type="enabled",
|
||||
budget_tokens=DEFAULT_REASONING_EFFORT_MEDIUM_THINKING_BUDGET,
|
||||
)
|
||||
elif reasoning_effort == "high":
|
||||
return AnthropicThinkingParam(
|
||||
type="enabled",
|
||||
budget_tokens=DEFAULT_REASONING_EFFORT_HIGH_THINKING_BUDGET,
|
||||
)
|
||||
elif reasoning_effort == "minimal":
|
||||
return AnthropicThinkingParam(
|
||||
type="enabled",
|
||||
budget_tokens=DEFAULT_REASONING_EFFORT_MINIMAL_THINKING_BUDGET,
|
||||
type="adaptive",
|
||||
)
|
||||
else:
|
||||
raise ValueError(f"Unmapped reasoning effort: {reasoning_effort}")
|
||||
if reasoning_effort is None:
|
||||
return None
|
||||
elif reasoning_effort == "low":
|
||||
return AnthropicThinkingParam(
|
||||
type="enabled",
|
||||
budget_tokens=DEFAULT_REASONING_EFFORT_LOW_THINKING_BUDGET,
|
||||
)
|
||||
elif reasoning_effort == "medium":
|
||||
return AnthropicThinkingParam(
|
||||
type="enabled",
|
||||
budget_tokens=DEFAULT_REASONING_EFFORT_MEDIUM_THINKING_BUDGET,
|
||||
)
|
||||
elif reasoning_effort == "high":
|
||||
return AnthropicThinkingParam(
|
||||
type="enabled",
|
||||
budget_tokens=DEFAULT_REASONING_EFFORT_HIGH_THINKING_BUDGET,
|
||||
)
|
||||
elif reasoning_effort == "minimal":
|
||||
return AnthropicThinkingParam(
|
||||
type="enabled",
|
||||
budget_tokens=DEFAULT_REASONING_EFFORT_MINIMAL_THINKING_BUDGET,
|
||||
)
|
||||
else:
|
||||
raise ValueError(f"Unmapped reasoning effort: {reasoning_effort}")
|
||||
|
||||
def _extract_json_schema_from_response_format(
|
||||
self, value: Optional[dict]
|
||||
|
|
@ -860,13 +867,8 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
if param == "thinking":
|
||||
optional_params["thinking"] = value
|
||||
elif param == "reasoning_effort" and isinstance(value, str):
|
||||
# For Claude Opus 4.5, map reasoning_effort to output_config
|
||||
if self._is_claude_opus_4_5(model):
|
||||
optional_params["output_config"] = {"effort": value}
|
||||
|
||||
# For other models, map to thinking parameter
|
||||
optional_params["thinking"] = AnthropicConfig._map_reasoning_effort(
|
||||
value
|
||||
reasoning_effort=value, model=model
|
||||
)
|
||||
elif param == "web_search_options" and isinstance(value, dict):
|
||||
hosted_web_search_tool = self.map_web_search_tool(
|
||||
|
|
@ -877,6 +879,9 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
)
|
||||
elif param == "extra_headers":
|
||||
optional_params["extra_headers"] = value
|
||||
elif param == "context_management" and isinstance(value, dict):
|
||||
# Pass through Anthropic-specific context_management parameter
|
||||
optional_params["context_management"] = value
|
||||
|
||||
## handle thinking tokens
|
||||
self.update_optional_params_with_thinking_tokens(
|
||||
|
|
@ -1026,9 +1031,37 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
if beta_value not in existing_values:
|
||||
headers["anthropic-beta"] = f"{existing_beta}, {beta_value}"
|
||||
|
||||
def _ensure_context_management_beta_header(self, headers: dict) -> None:
|
||||
beta_value = ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value
|
||||
self._ensure_beta_header(headers, beta_value)
|
||||
def _ensure_context_management_beta_header(
|
||||
self, headers: dict, context_management: dict
|
||||
) -> None:
|
||||
"""
|
||||
Add appropriate beta headers based on context_management edits.
|
||||
- If any edit has type "compact_20260112", add compact-2026-01-12 header
|
||||
- For all other edits, add context-management-2025-06-27 header
|
||||
"""
|
||||
edits = context_management.get("edits", [])
|
||||
|
||||
has_compact = False
|
||||
has_other = False
|
||||
|
||||
for edit in edits:
|
||||
edit_type = edit.get("type", "")
|
||||
if edit_type == "compact_20260112":
|
||||
has_compact = True
|
||||
else:
|
||||
has_other = True
|
||||
|
||||
# Add compact header if any compact edits exist
|
||||
if has_compact:
|
||||
self._ensure_beta_header(
|
||||
headers, ANTHROPIC_BETA_HEADER_VALUES.COMPACT_2026_01_12.value
|
||||
)
|
||||
|
||||
# Add context management header if any other edits exist
|
||||
if has_other:
|
||||
self._ensure_beta_header(
|
||||
headers, ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value
|
||||
)
|
||||
|
||||
def update_headers_with_optional_anthropic_beta(
|
||||
self, headers: dict, optional_params: dict
|
||||
|
|
@ -1056,7 +1089,9 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
headers, ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value
|
||||
)
|
||||
if optional_params.get("context_management") is not None:
|
||||
self._ensure_context_management_beta_header(headers)
|
||||
self._ensure_context_management_beta_header(
|
||||
headers, optional_params["context_management"]
|
||||
)
|
||||
if optional_params.get("output_format") is not None:
|
||||
self._ensure_beta_header(
|
||||
headers, ANTHROPIC_BETA_HEADER_VALUES.STRUCTURED_OUTPUT_2025_09_25.value
|
||||
|
|
@ -1225,6 +1260,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
List[ChatCompletionToolCallChunk],
|
||||
Optional[List[Any]],
|
||||
Optional[List[Any]],
|
||||
Optional[List[Any]],
|
||||
]:
|
||||
text_content = ""
|
||||
citations: Optional[List[Any]] = None
|
||||
|
|
@ -1237,6 +1273,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
tool_calls: List[ChatCompletionToolCallChunk] = []
|
||||
web_search_results: Optional[List[Any]] = None
|
||||
tool_results: Optional[List[Any]] = None
|
||||
compaction_blocks: Optional[List[Any]] = None
|
||||
for idx, content in enumerate(completion_response["content"]):
|
||||
if content["type"] == "text":
|
||||
text_content += content["text"]
|
||||
|
|
@ -1278,6 +1315,12 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
thinking_blocks.append(
|
||||
cast(ChatCompletionRedactedThinkingBlock, content)
|
||||
)
|
||||
|
||||
## COMPACTION
|
||||
elif content["type"] == "compaction":
|
||||
if compaction_blocks is None:
|
||||
compaction_blocks = []
|
||||
compaction_blocks.append(content)
|
||||
|
||||
## CITATIONS
|
||||
if content.get("citations") is not None:
|
||||
|
|
@ -1299,7 +1342,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
if thinking_content is not None:
|
||||
reasoning_content += thinking_content
|
||||
|
||||
return text_content, citations, thinking_blocks, reasoning_content, tool_calls, web_search_results, tool_results
|
||||
return text_content, citations, thinking_blocks, reasoning_content, tool_calls, web_search_results, tool_results, compaction_blocks
|
||||
|
||||
def calculate_usage(
|
||||
self,
|
||||
|
|
@ -1316,6 +1359,10 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
cache_creation_token_details: Optional[CacheCreationTokenDetails] = None
|
||||
web_search_requests: Optional[int] = None
|
||||
tool_search_requests: Optional[int] = None
|
||||
inference_geo: Optional[str] = None
|
||||
if "inference_geo" in _usage and _usage["inference_geo"] is not None:
|
||||
inference_geo = _usage["inference_geo"]
|
||||
|
||||
if (
|
||||
"cache_creation_input_tokens" in _usage
|
||||
and _usage["cache_creation_input_tokens"] is not None
|
||||
|
|
@ -1399,6 +1446,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
if (web_search_requests is not None or tool_search_requests is not None)
|
||||
else None
|
||||
),
|
||||
inference_geo=inference_geo,
|
||||
)
|
||||
return usage
|
||||
|
||||
|
|
@ -1442,6 +1490,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
tool_calls,
|
||||
web_search_results,
|
||||
tool_results,
|
||||
compaction_blocks,
|
||||
) = self.extract_response_content(completion_response=completion_response)
|
||||
|
||||
if (
|
||||
|
|
@ -1469,6 +1518,8 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
provider_specific_fields["tool_results"] = tool_results
|
||||
if container is not None:
|
||||
provider_specific_fields["container"] = container
|
||||
if compaction_blocks is not None:
|
||||
provider_specific_fields["compaction_blocks"] = compaction_blocks
|
||||
|
||||
_message = litellm.Message(
|
||||
tool_calls=tool_calls,
|
||||
|
|
@ -1477,6 +1528,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
thinking_blocks=thinking_blocks,
|
||||
reasoning_content=reasoning_content,
|
||||
)
|
||||
_message.provider_specific_fields = provider_specific_fields
|
||||
|
||||
## HANDLE JSON MODE - anthropic returns single function call
|
||||
json_mode_message = self._transform_response_for_json_mode(
|
||||
|
|
@ -1507,18 +1559,7 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
model_response.created = int(time.time())
|
||||
model_response.model = completion_response["model"]
|
||||
|
||||
context_management_response = completion_response.get("context_management")
|
||||
if context_management_response is not None:
|
||||
_hidden_params["context_management"] = context_management_response
|
||||
try:
|
||||
model_response.__dict__["context_management"] = (
|
||||
context_management_response
|
||||
)
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
model_response._hidden_params = _hidden_params
|
||||
|
||||
return model_response
|
||||
|
||||
def get_prefix_prompt(self, messages: List[AllMessageValues]) -> Optional[str]:
|
||||
|
|
|
|||
|
|
@ -22,10 +22,17 @@ def cost_per_token(model: str, usage: "Usage") -> Tuple[float, float]:
|
|||
Returns:
|
||||
Tuple[float, float] - prompt_cost_in_usd, completion_cost_in_usd
|
||||
"""
|
||||
return generic_cost_per_token(
|
||||
model=model, usage=usage, custom_llm_provider="anthropic"
|
||||
# If usage has inference_geo, prepend it as prefix to model name
|
||||
if hasattr(usage, "inference_geo") and usage.inference_geo and usage.inference_geo.lower() not in ["global", "not_available"]:
|
||||
model_with_geo_prefix = f"{usage.inference_geo}/{model}"
|
||||
else:
|
||||
model_with_geo_prefix = model
|
||||
prompt_cost, completion_cost = generic_cost_per_token(
|
||||
model=model_with_geo_prefix, usage=usage, custom_llm_provider="anthropic"
|
||||
)
|
||||
|
||||
return prompt_cost, completion_cost
|
||||
|
||||
|
||||
def get_cost_for_anthropic_web_search(
|
||||
model_info: Optional["ModelInfo"] = None,
|
||||
|
|
|
|||
|
|
@ -6,6 +6,7 @@ from typing import (
|
|||
Dict,
|
||||
List,
|
||||
Optional,
|
||||
Tuple,
|
||||
Union,
|
||||
cast,
|
||||
)
|
||||
|
|
@ -47,8 +48,14 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
top_p: Optional[float] = None,
|
||||
output_format: Optional[Dict] = None,
|
||||
extra_kwargs: Optional[Dict[str, Any]] = None,
|
||||
) -> Dict[str, Any]:
|
||||
"""Prepare kwargs for litellm.completion/acompletion"""
|
||||
) -> Tuple[Dict[str, Any], Dict[str, str]]:
|
||||
"""Prepare kwargs for litellm.completion/acompletion.
|
||||
|
||||
Returns:
|
||||
Tuple of (completion_kwargs, tool_name_mapping)
|
||||
- tool_name_mapping maps truncated tool names back to original names
|
||||
for tools that exceeded OpenAI's 64-char limit
|
||||
"""
|
||||
from litellm.litellm_core_utils.litellm_logging import (
|
||||
Logging as LiteLLMLoggingObject,
|
||||
)
|
||||
|
|
@ -80,7 +87,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
if output_format:
|
||||
request_data["output_format"] = output_format
|
||||
|
||||
openai_request = ANTHROPIC_ADAPTER.translate_completion_input_params(
|
||||
openai_request, tool_name_mapping = ANTHROPIC_ADAPTER.translate_completion_input_params_with_tool_mapping(
|
||||
request_data
|
||||
)
|
||||
|
||||
|
|
@ -116,7 +123,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
):
|
||||
completion_kwargs[key] = value
|
||||
|
||||
return completion_kwargs
|
||||
return completion_kwargs, tool_name_mapping
|
||||
|
||||
@staticmethod
|
||||
async def async_anthropic_messages_handler(
|
||||
|
|
@ -137,7 +144,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
**kwargs,
|
||||
) -> Union[AnthropicMessagesResponse, AsyncIterator]:
|
||||
"""Handle non-Anthropic models asynchronously using the adapter"""
|
||||
completion_kwargs = (
|
||||
completion_kwargs, tool_name_mapping = (
|
||||
LiteLLMMessagesToCompletionTransformationHandler._prepare_completion_kwargs(
|
||||
max_tokens=max_tokens,
|
||||
messages=messages,
|
||||
|
|
@ -164,6 +171,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
ANTHROPIC_ADAPTER.translate_completion_output_params_streaming(
|
||||
completion_response,
|
||||
model=model,
|
||||
tool_name_mapping=tool_name_mapping,
|
||||
)
|
||||
)
|
||||
if transformed_stream is not None:
|
||||
|
|
@ -172,7 +180,8 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
else:
|
||||
anthropic_response = (
|
||||
ANTHROPIC_ADAPTER.translate_completion_output_params(
|
||||
cast(ModelResponse, completion_response)
|
||||
cast(ModelResponse, completion_response),
|
||||
tool_name_mapping=tool_name_mapping,
|
||||
)
|
||||
)
|
||||
if anthropic_response is not None:
|
||||
|
|
@ -222,7 +231,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
**kwargs,
|
||||
)
|
||||
|
||||
completion_kwargs = (
|
||||
completion_kwargs, tool_name_mapping = (
|
||||
LiteLLMMessagesToCompletionTransformationHandler._prepare_completion_kwargs(
|
||||
max_tokens=max_tokens,
|
||||
messages=messages,
|
||||
|
|
@ -249,6 +258,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
ANTHROPIC_ADAPTER.translate_completion_output_params_streaming(
|
||||
completion_response,
|
||||
model=model,
|
||||
tool_name_mapping=tool_name_mapping,
|
||||
)
|
||||
)
|
||||
if transformed_stream is not None:
|
||||
|
|
@ -257,7 +267,8 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
else:
|
||||
anthropic_response = (
|
||||
ANTHROPIC_ADAPTER.translate_completion_output_params(
|
||||
cast(ModelResponse, completion_response)
|
||||
cast(ModelResponse, completion_response),
|
||||
tool_name_mapping=tool_name_mapping,
|
||||
)
|
||||
)
|
||||
if anthropic_response is not None:
|
||||
|
|
|
|||
|
|
@ -3,7 +3,7 @@
|
|||
import json
|
||||
import traceback
|
||||
from collections import deque
|
||||
from typing import TYPE_CHECKING, Any, AsyncIterator, Iterator, Literal, Optional
|
||||
from typing import TYPE_CHECKING, Any, AsyncIterator, Dict, Iterator, Literal, Optional
|
||||
|
||||
from litellm import verbose_logger
|
||||
from litellm._uuid import uuid
|
||||
|
|
@ -44,9 +44,16 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
|
|||
pending_new_content_block: bool = False
|
||||
chunk_queue: deque = deque() # Queue for buffering multiple chunks
|
||||
|
||||
def __init__(self, completion_stream: Any, model: str):
|
||||
def __init__(
|
||||
self,
|
||||
completion_stream: Any,
|
||||
model: str,
|
||||
tool_name_mapping: Optional[Dict[str, str]] = None,
|
||||
):
|
||||
super().__init__(completion_stream)
|
||||
self.model = model
|
||||
# Mapping of truncated tool names to original names (for OpenAI's 64-char limit)
|
||||
self.tool_name_mapping = tool_name_mapping or {}
|
||||
|
||||
def _create_initial_usage_delta(self) -> UsageDelta:
|
||||
"""
|
||||
|
|
@ -401,6 +408,19 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
|
|||
choices=chunk.choices # type: ignore
|
||||
)
|
||||
|
||||
# Restore original tool name if it was truncated for OpenAI's 64-char limit
|
||||
if block_type == "tool_use":
|
||||
# Type narrowing: content_block_start is ToolUseBlock when block_type is "tool_use"
|
||||
from typing import cast
|
||||
from litellm.types.llms.anthropic import ToolUseBlock
|
||||
|
||||
tool_block = cast(ToolUseBlock, content_block_start)
|
||||
|
||||
if tool_block.get("name"):
|
||||
truncated_name = tool_block["name"]
|
||||
original_name = self.tool_name_mapping.get(truncated_name, truncated_name)
|
||||
tool_block["name"] = original_name
|
||||
|
||||
if block_type != self.current_content_block_type:
|
||||
self.current_content_block_type = block_type
|
||||
self.current_content_block_start = content_block_start
|
||||
|
|
@ -408,9 +428,14 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
|
|||
|
||||
# For parallel tool calls, we'll necessarily have a new content block
|
||||
# if we get a function name since it signals a new tool call
|
||||
if block_type == "tool_use" and content_block_start.get("name"):
|
||||
self.current_content_block_type = block_type
|
||||
self.current_content_block_start = content_block_start
|
||||
return True
|
||||
if block_type == "tool_use":
|
||||
from typing import cast
|
||||
from litellm.types.llms.anthropic import ToolUseBlock
|
||||
|
||||
tool_block = cast(ToolUseBlock, content_block_start)
|
||||
if tool_block.get("name"):
|
||||
self.current_content_block_type = block_type
|
||||
self.current_content_block_start = content_block_start
|
||||
return True
|
||||
|
||||
return False
|
||||
|
|
|
|||
|
|
@ -1,3 +1,4 @@
|
|||
import hashlib
|
||||
import json
|
||||
from typing import (
|
||||
TYPE_CHECKING,
|
||||
|
|
@ -12,6 +13,54 @@ from typing import (
|
|||
cast,
|
||||
)
|
||||
|
||||
# OpenAI has a 64-character limit for function/tool names
|
||||
# Anthropic does not have this limit, so we need to truncate long names
|
||||
OPENAI_MAX_TOOL_NAME_LENGTH = 64
|
||||
TOOL_NAME_HASH_LENGTH = 8
|
||||
TOOL_NAME_PREFIX_LENGTH = OPENAI_MAX_TOOL_NAME_LENGTH - TOOL_NAME_HASH_LENGTH - 1 # 55
|
||||
|
||||
|
||||
def truncate_tool_name(name: str) -> str:
|
||||
"""
|
||||
Truncate tool names that exceed OpenAI's 64-character limit.
|
||||
|
||||
Uses format: {55-char-prefix}_{8-char-hash} to avoid collisions
|
||||
when multiple tools have similar long names.
|
||||
|
||||
Args:
|
||||
name: The original tool name
|
||||
|
||||
Returns:
|
||||
The original name if <= 64 chars, otherwise truncated with hash
|
||||
"""
|
||||
if len(name) <= OPENAI_MAX_TOOL_NAME_LENGTH:
|
||||
return name
|
||||
|
||||
# Create deterministic hash from full name to avoid collisions
|
||||
name_hash = hashlib.sha256(name.encode()).hexdigest()[:TOOL_NAME_HASH_LENGTH]
|
||||
return f"{name[:TOOL_NAME_PREFIX_LENGTH]}_{name_hash}"
|
||||
|
||||
|
||||
def create_tool_name_mapping(
|
||||
tools: List[Dict[str, Any]],
|
||||
) -> Dict[str, str]:
|
||||
"""
|
||||
Create a mapping of truncated tool names to original names.
|
||||
|
||||
Args:
|
||||
tools: List of tool definitions with 'name' field
|
||||
|
||||
Returns:
|
||||
Dict mapping truncated names to original names (only for truncated tools)
|
||||
"""
|
||||
mapping: Dict[str, str] = {}
|
||||
for tool in tools:
|
||||
original_name = tool.get("name", "")
|
||||
truncated_name = truncate_tool_name(original_name)
|
||||
if truncated_name != original_name:
|
||||
mapping[truncated_name] = original_name
|
||||
return mapping
|
||||
|
||||
from openai.types.chat.chat_completion_chunk import Choice as OpenAIStreamingChoice
|
||||
|
||||
from litellm.litellm_core_utils.prompt_templates.common_utils import (
|
||||
|
|
@ -77,8 +126,29 @@ class AnthropicAdapter:
|
|||
self, kwargs
|
||||
) -> Optional[ChatCompletionRequest]:
|
||||
"""
|
||||
Translate Anthropic request params to OpenAI format.
|
||||
|
||||
- translate params, where needed
|
||||
- pass rest, as is
|
||||
|
||||
Note: Use translate_completion_input_params_with_tool_mapping() if you need
|
||||
the tool name mapping for restoring original names in responses.
|
||||
"""
|
||||
result, _ = self.translate_completion_input_params_with_tool_mapping(kwargs)
|
||||
return result
|
||||
|
||||
def translate_completion_input_params_with_tool_mapping(
|
||||
self, kwargs
|
||||
) -> Tuple[Optional[ChatCompletionRequest], Dict[str, str]]:
|
||||
"""
|
||||
Translate Anthropic request params to OpenAI format, returning tool name mapping.
|
||||
|
||||
This method handles truncation of tool names that exceed OpenAI's 64-character
|
||||
limit. The mapping allows restoring original names when translating responses.
|
||||
|
||||
Returns:
|
||||
Tuple of (openai_request, tool_name_mapping)
|
||||
- tool_name_mapping maps truncated tool names back to original names
|
||||
"""
|
||||
|
||||
#########################################################
|
||||
|
|
@ -102,26 +172,51 @@ class AnthropicAdapter:
|
|||
model=model, messages=messages, **kwargs
|
||||
)
|
||||
|
||||
translated_body = (
|
||||
translated_body, tool_name_mapping = (
|
||||
LiteLLMAnthropicMessagesAdapter().translate_anthropic_to_openai(
|
||||
anthropic_message_request=request_body
|
||||
)
|
||||
)
|
||||
|
||||
return translated_body
|
||||
return translated_body, tool_name_mapping
|
||||
|
||||
def translate_completion_output_params(
|
||||
self, response: ModelResponse
|
||||
self,
|
||||
response: ModelResponse,
|
||||
tool_name_mapping: Optional[Dict[str, str]] = None,
|
||||
) -> Optional[AnthropicMessagesResponse]:
|
||||
"""
|
||||
Translate OpenAI response to Anthropic format.
|
||||
|
||||
Args:
|
||||
response: The OpenAI ModelResponse
|
||||
tool_name_mapping: Optional mapping of truncated tool names to original names.
|
||||
Used to restore original names for tools that exceeded
|
||||
OpenAI's 64-char limit.
|
||||
"""
|
||||
return LiteLLMAnthropicMessagesAdapter().translate_openai_response_to_anthropic(
|
||||
response=response
|
||||
response=response,
|
||||
tool_name_mapping=tool_name_mapping,
|
||||
)
|
||||
|
||||
def translate_completion_output_params_streaming(
|
||||
self, completion_stream: Any, model: str
|
||||
self,
|
||||
completion_stream: Any,
|
||||
model: str,
|
||||
tool_name_mapping: Optional[Dict[str, str]] = None,
|
||||
) -> Union[AsyncIterator[bytes], None]:
|
||||
"""
|
||||
Translate OpenAI streaming response to Anthropic format.
|
||||
|
||||
Args:
|
||||
completion_stream: The OpenAI streaming response
|
||||
model: The model name
|
||||
tool_name_mapping: Optional mapping of truncated tool names to original names.
|
||||
"""
|
||||
anthropic_wrapper = AnthropicStreamWrapper(
|
||||
completion_stream=completion_stream, model=model
|
||||
completion_stream=completion_stream,
|
||||
model=model,
|
||||
tool_name_mapping=tool_name_mapping,
|
||||
)
|
||||
# Return the SSE-wrapped version for proper event formatting
|
||||
return anthropic_wrapper.async_anthropic_sse_wrapper()
|
||||
|
|
@ -417,8 +512,10 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
has_cache_control_in_text = True
|
||||
assistant_content_list.append(text_block)
|
||||
elif content.get("type") == "tool_use":
|
||||
# Truncate tool name for OpenAI's 64-char limit
|
||||
tool_name = truncate_tool_name(content.get("name", ""))
|
||||
function_chunk: ChatCompletionToolCallFunctionChunk = {
|
||||
"name": content.get("name", ""),
|
||||
"name": tool_name,
|
||||
"arguments": json.dumps(content.get("input", {})),
|
||||
}
|
||||
signature = (
|
||||
|
|
@ -587,8 +684,11 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
elif tool_choice["type"] == "auto":
|
||||
return "auto"
|
||||
elif tool_choice["type"] == "tool":
|
||||
# Truncate tool name if it exceeds OpenAI's 64-char limit
|
||||
original_name = tool_choice.get("name", "")
|
||||
truncated_name = truncate_tool_name(original_name)
|
||||
tc_function_param = ChatCompletionToolChoiceFunctionParam(
|
||||
name=tool_choice.get("name", "")
|
||||
name=truncated_name
|
||||
)
|
||||
return ChatCompletionToolChoiceObjectParam(
|
||||
type="function", function=tc_function_param
|
||||
|
|
@ -600,12 +700,28 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
|
||||
def translate_anthropic_tools_to_openai(
|
||||
self, tools: List[AllAnthropicToolsValues], model: Optional[str] = None
|
||||
) -> List[ChatCompletionToolParam]:
|
||||
) -> Tuple[List[ChatCompletionToolParam], Dict[str, str]]:
|
||||
"""
|
||||
Translate Anthropic tools to OpenAI format.
|
||||
|
||||
Returns:
|
||||
Tuple of (translated_tools, tool_name_mapping)
|
||||
- tool_name_mapping maps truncated names back to original names
|
||||
for tools that exceeded OpenAI's 64-char limit
|
||||
"""
|
||||
new_tools: List[ChatCompletionToolParam] = []
|
||||
tool_name_mapping: Dict[str, str] = {}
|
||||
mapped_tool_params = ["name", "input_schema", "description", "cache_control"]
|
||||
for tool in tools:
|
||||
original_name = tool["name"]
|
||||
truncated_name = truncate_tool_name(original_name)
|
||||
|
||||
# Store mapping if name was truncated
|
||||
if truncated_name != original_name:
|
||||
tool_name_mapping[truncated_name] = original_name
|
||||
|
||||
function_chunk = ChatCompletionToolParamFunctionChunk(
|
||||
name=tool["name"],
|
||||
name=truncated_name,
|
||||
)
|
||||
if "input_schema" in tool:
|
||||
function_chunk["parameters"] = tool["input_schema"] # type: ignore
|
||||
|
|
@ -619,7 +735,7 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
self._add_cache_control_if_applicable(tool, tool_param, model)
|
||||
new_tools.append(tool_param) # type: ignore[arg-type]
|
||||
|
||||
return new_tools # type: ignore[return-value]
|
||||
return new_tools, tool_name_mapping # type: ignore[return-value]
|
||||
|
||||
def translate_anthropic_output_format_to_openai(
|
||||
self, output_format: Any
|
||||
|
|
@ -694,12 +810,18 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
|
||||
def translate_anthropic_to_openai(
|
||||
self, anthropic_message_request: AnthropicMessagesRequest
|
||||
) -> ChatCompletionRequest:
|
||||
) -> Tuple[ChatCompletionRequest, Dict[str, str]]:
|
||||
"""
|
||||
This is used by the beta Anthropic Adapter, for translating anthropic `/v1/messages` requests to the openai format.
|
||||
|
||||
Returns:
|
||||
Tuple of (openai_request, tool_name_mapping)
|
||||
- tool_name_mapping maps truncated tool names back to original names
|
||||
for tools that exceeded OpenAI's 64-char limit
|
||||
"""
|
||||
# Debug: Processing Anthropic message request
|
||||
new_messages: List[AllMessageValues] = []
|
||||
tool_name_mapping: Dict[str, str] = {}
|
||||
|
||||
## CONVERT ANTHROPIC MESSAGES TO OPENAI
|
||||
messages_list: List[
|
||||
|
|
@ -750,7 +872,7 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
if "tools" in anthropic_message_request:
|
||||
tools = anthropic_message_request["tools"]
|
||||
if tools:
|
||||
new_kwargs["tools"] = self.translate_anthropic_tools_to_openai(
|
||||
new_kwargs["tools"], tool_name_mapping = self.translate_anthropic_tools_to_openai(
|
||||
tools=cast(List[AllAnthropicToolsValues], tools),
|
||||
model=new_kwargs.get("model"),
|
||||
)
|
||||
|
|
@ -784,7 +906,7 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
if k not in translatable_params: # pass remaining params as is
|
||||
new_kwargs[k] = v # type: ignore
|
||||
|
||||
return new_kwargs
|
||||
return new_kwargs, tool_name_mapping
|
||||
|
||||
def _translate_anthropic_image_to_openai(self, image_source: dict) -> Optional[str]:
|
||||
"""
|
||||
|
|
@ -813,22 +935,12 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
|
||||
return None
|
||||
|
||||
def _translate_openai_content_to_anthropic(self, choices: List[Choices]) -> List[
|
||||
Union[
|
||||
AnthropicResponseContentBlockText,
|
||||
AnthropicResponseContentBlockToolUse,
|
||||
AnthropicResponseContentBlockThinking,
|
||||
AnthropicResponseContentBlockRedactedThinking,
|
||||
]
|
||||
]:
|
||||
new_content: List[
|
||||
Union[
|
||||
AnthropicResponseContentBlockText,
|
||||
AnthropicResponseContentBlockToolUse,
|
||||
AnthropicResponseContentBlockThinking,
|
||||
AnthropicResponseContentBlockRedactedThinking,
|
||||
]
|
||||
] = []
|
||||
def _translate_openai_content_to_anthropic(
|
||||
self,
|
||||
choices: List[Choices],
|
||||
tool_name_mapping: Optional[Dict[str, str]] = None,
|
||||
) -> List[Dict[str, Any]]:
|
||||
new_content: List[Dict[str, Any]] = []
|
||||
for choice in choices:
|
||||
# Handle thinking blocks first
|
||||
if (
|
||||
|
|
@ -852,7 +964,7 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
if signature_value is not None
|
||||
else None
|
||||
),
|
||||
)
|
||||
).model_dump()
|
||||
)
|
||||
elif thinking_block.get("type") == "redacted_thinking":
|
||||
data_value = thinking_block.get("data", "")
|
||||
|
|
@ -860,15 +972,27 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
AnthropicResponseContentBlockRedactedThinking(
|
||||
type="redacted_thinking",
|
||||
data=str(data_value) if data_value is not None else "",
|
||||
)
|
||||
).model_dump()
|
||||
)
|
||||
# Handle reasoning_content when thinking_blocks is not present
|
||||
elif (
|
||||
hasattr(choice.message, "reasoning_content")
|
||||
and choice.message.reasoning_content
|
||||
):
|
||||
new_content.append(
|
||||
AnthropicResponseContentBlockThinking(
|
||||
type="thinking",
|
||||
thinking=str(choice.message.reasoning_content),
|
||||
signature=None,
|
||||
).model_dump()
|
||||
)
|
||||
|
||||
# Handle text content
|
||||
if choice.message.content is not None:
|
||||
new_content.append(
|
||||
AnthropicResponseContentBlockText(
|
||||
type="text", text=choice.message.content
|
||||
)
|
||||
).model_dump()
|
||||
)
|
||||
# Handle tool calls (in parallel to text content)
|
||||
if (
|
||||
|
|
@ -883,13 +1007,21 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
if signature:
|
||||
provider_specific_fields["signature"] = signature
|
||||
|
||||
# Restore original tool name if it was truncated
|
||||
truncated_name = tool_call.function.name or ""
|
||||
original_name = (
|
||||
tool_name_mapping.get(truncated_name, truncated_name)
|
||||
if tool_name_mapping
|
||||
else truncated_name
|
||||
)
|
||||
|
||||
tool_use_block = AnthropicResponseContentBlockToolUse(
|
||||
type="tool_use",
|
||||
id=tool_call.id,
|
||||
name=tool_call.function.name or "",
|
||||
name=original_name,
|
||||
input=parse_tool_call_arguments(
|
||||
tool_call.function.arguments,
|
||||
tool_name=tool_call.function.name,
|
||||
tool_name=original_name,
|
||||
context="Anthropic pass-through adapter",
|
||||
),
|
||||
)
|
||||
|
|
@ -898,7 +1030,7 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
tool_use_block.provider_specific_fields = (
|
||||
provider_specific_fields
|
||||
)
|
||||
new_content.append(tool_use_block)
|
||||
new_content.append(tool_use_block.model_dump())
|
||||
|
||||
return new_content
|
||||
|
||||
|
|
@ -914,10 +1046,24 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
return "end_turn"
|
||||
|
||||
def translate_openai_response_to_anthropic(
|
||||
self, response: ModelResponse
|
||||
self,
|
||||
response: ModelResponse,
|
||||
tool_name_mapping: Optional[Dict[str, str]] = None,
|
||||
) -> AnthropicMessagesResponse:
|
||||
"""
|
||||
Translate OpenAI response to Anthropic format.
|
||||
|
||||
Args:
|
||||
response: The OpenAI ModelResponse
|
||||
tool_name_mapping: Optional mapping of truncated tool names to original names.
|
||||
Used to restore original names for tools that exceeded
|
||||
OpenAI's 64-char limit.
|
||||
"""
|
||||
## translate content block
|
||||
anthropic_content = self._translate_openai_content_to_anthropic(choices=response.choices) # type: ignore
|
||||
anthropic_content = self._translate_openai_content_to_anthropic(
|
||||
choices=response.choices, # type: ignore
|
||||
tool_name_mapping=tool_name_mapping,
|
||||
)
|
||||
## extract finish reason
|
||||
anthropic_finish_reason = self._translate_openai_finish_reason_to_anthropic(
|
||||
openai_finish_reason=response.choices[0].finish_reason # type: ignore
|
||||
|
|
@ -1036,6 +1182,13 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
|
||||
reasoning_content += thinking
|
||||
reasoning_signature += signature
|
||||
# Handle reasoning_content when thinking_blocks is not present
|
||||
# This handles providers like OpenRouter that return reasoning_content
|
||||
elif isinstance(choice, StreamingChoices) and hasattr(
|
||||
choice.delta, "reasoning_content"
|
||||
):
|
||||
if choice.delta.reasoning_content is not None:
|
||||
reasoning_content += choice.delta.reasoning_content
|
||||
|
||||
if reasoning_content and reasoning_signature:
|
||||
raise ValueError(
|
||||
|
|
|
|||
|
|
@ -2,6 +2,9 @@ from typing import Any, AsyncIterator, Dict, List, Optional, Tuple
|
|||
|
||||
import httpx
|
||||
|
||||
from litellm.anthropic_beta_headers_manager import (
|
||||
update_headers_with_filtered_beta,
|
||||
)
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj
|
||||
from litellm.litellm_core_utils.litellm_logging import verbose_logger
|
||||
from litellm.llms.base_llm.anthropic_messages.transformation import (
|
||||
|
|
@ -90,6 +93,11 @@ class AnthropicMessagesConfig(BaseAnthropicMessagesConfig):
|
|||
optional_params=optional_params,
|
||||
)
|
||||
|
||||
headers = update_headers_with_filtered_beta(
|
||||
headers=headers,
|
||||
provider="anthropic",
|
||||
)
|
||||
|
||||
return headers, api_base
|
||||
|
||||
def transform_anthropic_messages_request(
|
||||
|
|
@ -189,8 +197,27 @@ class AnthropicMessagesConfig(BaseAnthropicMessagesConfig):
|
|||
beta_values.update(b.strip() for b in existing_beta.split(","))
|
||||
|
||||
# Check for context management
|
||||
if optional_params.get("context_management") is not None:
|
||||
beta_values.add(ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value)
|
||||
context_management_param = optional_params.get("context_management")
|
||||
if context_management_param is not None:
|
||||
# Check edits array for compact_20260112 type
|
||||
edits = context_management_param.get("edits", [])
|
||||
has_compact = False
|
||||
has_other = False
|
||||
|
||||
for edit in edits:
|
||||
edit_type = edit.get("type", "")
|
||||
if edit_type == "compact_20260112":
|
||||
has_compact = True
|
||||
else:
|
||||
has_other = True
|
||||
|
||||
# Add compact header if any compact edits exist
|
||||
if has_compact:
|
||||
beta_values.add(ANTHROPIC_BETA_HEADER_VALUES.COMPACT_2026_01_12.value)
|
||||
|
||||
# Add context management header if any other edits exist
|
||||
if has_other:
|
||||
beta_values.add(ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value)
|
||||
|
||||
# Check for structured outputs
|
||||
if optional_params.get("output_format") is not None:
|
||||
|
|
|
|||
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue