mirror of
https://github.com/BerriAI/litellm.git
synced 2026-10-10 03:28:53 +00:00
Merge remote-tracking branch 'origin' into litellm_sso_map_teams
This commit is contained in:
 yuneng-jiang
commit
1f51f067eb
391 changed files with 13700 additions and 19699 deletions
|
|
@ -3754,6 +3754,9 @@ jobs:
|
|||
|
||||
cd ui/litellm-dashboard
|
||||
|
||||
# Remove node_modules and package-lock to ensure clean install (fixes dependency resolution issues)
|
||||
rm -rf node_modules package-lock.json
|
||||
|
||||
# Install dependencies first
|
||||
npm install
|
||||
|
||||
|
|
|
|||
1
.gitignore
vendored
1
.gitignore
vendored
|
|
@ -95,6 +95,7 @@ update_model_cost_map.py
|
|||
tests/test_litellm/proxy/_experimental/mcp_server/test_mcp_server_manager.py
|
||||
scripts/test_vertex_ai_search.py
|
||||
LAZY_LOADING_IMPROVEMENTS.md
|
||||
STABILIZATION_TODO.md
|
||||
**/test-results
|
||||
**/playwright-report
|
||||
**/*.storageState.json
|
||||
|
|
|
|||
12
.trivyignore
Normal file
12
.trivyignore
Normal file
|
|
@ -0,0 +1,12 @@
|
|||
# LiteLLM Trivy Ignore File
|
||||
# CVEs listed here are temporarily allowlisted pending fixes
|
||||
|
||||
# Next.js vulnerabilities in UI dashboard (next@14.2.35)
|
||||
# Allowlisted: 2026-01-31, 7-day fix timeline
|
||||
# Fix: Upgrade to Next.js 15.5.10+ or 16.1.5+
|
||||
|
||||
# HIGH: DoS via request deserialization
|
||||
GHSA-h25m-26qc-wcjf
|
||||
|
||||
# MEDIUM: Image Optimizer DoS
|
||||
CVE-2025-59471
|
||||
|
|
@ -47,7 +47,8 @@ FROM $LITELLM_RUNTIME_IMAGE AS runtime
|
|||
USER root
|
||||
|
||||
# Install runtime dependencies (libsndfile needed for audio processing on ARM64)
|
||||
RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip libsndfile
|
||||
RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip libsndfile && \
|
||||
npm install -g npm@latest tar@latest
|
||||
|
||||
WORKDIR /app
|
||||
# Copy the current directory contents into the container at /app
|
||||
|
|
|
|||
|
|
@ -81,10 +81,10 @@ run_trivy_scans() {
|
|||
echo "Running Trivy scans..."
|
||||
|
||||
echo "Scanning LiteLLM Docs..."
|
||||
trivy fs --scanners vuln --dependency-tree --exit-code 1 --severity HIGH,CRITICAL,MEDIUM ./docs/
|
||||
trivy fs --ignorefile .trivyignore --scanners vuln --dependency-tree --exit-code 1 --severity HIGH,CRITICAL,MEDIUM ./docs/
|
||||
|
||||
echo "Scanning LiteLLM UI..."
|
||||
trivy fs --scanners vuln --dependency-tree --exit-code 1 --severity HIGH,CRITICAL,MEDIUM ./ui/
|
||||
trivy fs --ignorefile .trivyignore --scanners vuln --dependency-tree --exit-code 1 --severity HIGH,CRITICAL,MEDIUM ./ui/
|
||||
|
||||
echo "Trivy scans completed successfully"
|
||||
}
|
||||
|
|
@ -137,6 +137,7 @@ run_grype_scans() {
|
|||
"CVE-2019-1010025" # glibc pthread heap address leak - awaiting patched Wolfi glibc build
|
||||
"CVE-2026-22184" # zlib untgz buffer overflow - untgz unused + no fixed Wolfi build yet
|
||||
"GHSA-58pv-8j8x-9vj2" # jaraco.context path traversal - setuptools vendored only (v5.3.0), not used in application code (using v6.1.0+)
|
||||
"GHSA-34x7-hfp2-rc4v" # node-tar hardlink path traversal - not applicable, tar CLI not exposed in application code
|
||||
"GHSA-r6q2-hw4h-h46w" # node-tar not used by application runtime, Linux-only container, not affect by macOS APFS-specific exploit
|
||||
"GHSA-8rrh-rw8j-w5fx" # wheel is from chainguard and will be handled by then TODO: Remove this after Chainguard updates the wheel
|
||||
"CVE-2025-59465" # We do not use Node in application runtime, only used for building Admin UI
|
||||
|
|
|
|||
284
cookbook/nova_sonic_realtime.py
Normal file
284
cookbook/nova_sonic_realtime.py
Normal file
|
|
@ -0,0 +1,284 @@
|
|||
"""
|
||||
Client script to test Nova Sonic realtime API through LiteLLM proxy.
|
||||
|
||||
This script connects to LiteLLM proxy's realtime endpoint and enables
|
||||
speech-to-speech conversation with Bedrock Nova Sonic.
|
||||
|
||||
Prerequisites:
|
||||
- LiteLLM proxy running with Bedrock configured
|
||||
- pyaudio installed: pip install pyaudio
|
||||
- websockets installed: pip install websockets
|
||||
|
||||
Usage:
|
||||
python nova_sonic_realtime.py
|
||||
"""
|
||||
|
||||
import asyncio
|
||||
import base64
|
||||
import json
|
||||
import pyaudio
|
||||
import websockets
|
||||
from typing import Optional
|
||||
|
||||
# Audio configuration (matching Nova Sonic requirements)
|
||||
INPUT_SAMPLE_RATE = 16000 # Nova Sonic expects 16kHz input
|
||||
OUTPUT_SAMPLE_RATE = 24000 # Nova Sonic outputs 24kHz
|
||||
CHANNELS = 1
|
||||
FORMAT = pyaudio.paInt16
|
||||
CHUNK_SIZE = 1024
|
||||
|
||||
# LiteLLM proxy configuration
|
||||
LITELLM_PROXY_URL = "ws://localhost:4000/v1/realtime?model=bedrock-sonic"
|
||||
LITELLM_API_KEY = "sk-12345" # Your LiteLLM API key
|
||||
|
||||
|
||||
class RealtimeClient:
|
||||
"""Client for LiteLLM realtime API with audio support."""
|
||||
|
||||
def __init__(self, url: str, api_key: str):
|
||||
self.url = url
|
||||
self.api_key = api_key
|
||||
self.ws: Optional[websockets.WebSocketClientProtocol] = None
|
||||
self.is_active = False
|
||||
self.audio_queue = asyncio.Queue()
|
||||
self.pyaudio = pyaudio.PyAudio()
|
||||
self.input_stream = None
|
||||
self.output_stream = None
|
||||
|
||||
async def connect(self):
|
||||
"""Connect to LiteLLM proxy realtime endpoint."""
|
||||
print(f"Connecting to {self.url}...")
|
||||
|
||||
headers = {}
|
||||
if self.api_key:
|
||||
headers["Authorization"] = f"Bearer {self.api_key}"
|
||||
|
||||
self.ws = await websockets.connect(
|
||||
self.url,
|
||||
additional_headers=headers,
|
||||
max_size=10 * 1024 * 1024, # 10MB max message size
|
||||
)
|
||||
self.is_active = True
|
||||
print("✓ Connected to LiteLLM proxy")
|
||||
|
||||
async def send_session_update(self):
|
||||
"""Send session configuration."""
|
||||
session_update = {
|
||||
"type": "session.update",
|
||||
"session": {
|
||||
"instructions": "You are a friendly assistant. Keep your responses short and conversational.",
|
||||
"voice": "matthew",
|
||||
"temperature": 0.8,
|
||||
"max_response_output_tokens": 1024,
|
||||
"modalities": ["text", "audio"],
|
||||
"input_audio_format": "pcm16",
|
||||
"output_audio_format": "pcm16",
|
||||
"turn_detection": {
|
||||
"type": "server_vad",
|
||||
"threshold": 0.5,
|
||||
"prefix_padding_ms": 300,
|
||||
"silence_duration_ms": 500,
|
||||
},
|
||||
},
|
||||
}
|
||||
await self.ws.send(json.dumps(session_update))
|
||||
print("✓ Session configuration sent")
|
||||
|
||||
async def receive_messages(self):
|
||||
"""Receive and process messages from the server."""
|
||||
try:
|
||||
async for message in self.ws:
|
||||
if not self.is_active:
|
||||
break
|
||||
|
||||
try:
|
||||
data = json.loads(message)
|
||||
event_type = data.get("type")
|
||||
|
||||
if event_type == "session.created":
|
||||
print(f"✓ Session created: {data.get('session', {}).get('id')}")
|
||||
|
||||
elif event_type == "response.created":
|
||||
print("🤖 Assistant is responding...")
|
||||
|
||||
elif event_type == "response.text.delta":
|
||||
# Print text transcription
|
||||
delta = data.get("delta", "")
|
||||
print(delta, end="", flush=True)
|
||||
|
||||
elif event_type == "response.audio.delta":
|
||||
# Queue audio for playback
|
||||
audio_b64 = data.get("delta", "")
|
||||
if audio_b64:
|
||||
audio_bytes = base64.b64decode(audio_b64)
|
||||
await self.audio_queue.put(audio_bytes)
|
||||
|
||||
elif event_type == "response.text.done":
|
||||
print() # New line after text
|
||||
|
||||
elif event_type == "response.done":
|
||||
print("✓ Response complete")
|
||||
|
||||
elif event_type == "error":
|
||||
print(f"❌ Error: {data.get('error', {})}")
|
||||
|
||||
else:
|
||||
# Debug: print other event types
|
||||
print(f"[{event_type}]", end=" ")
|
||||
|
||||
except json.JSONDecodeError:
|
||||
print(f"Failed to parse message: {message[:100]}")
|
||||
|
||||
except websockets.exceptions.ConnectionClosed:
|
||||
print("\n✗ Connection closed")
|
||||
except Exception as e:
|
||||
print(f"\n✗ Error receiving messages: {e}")
|
||||
finally:
|
||||
self.is_active = False
|
||||
|
||||
async def send_audio_chunk(self, audio_bytes: bytes):
|
||||
"""Send audio chunk to server."""
|
||||
if not self.is_active or not self.ws:
|
||||
return
|
||||
|
||||
audio_b64 = base64.b64encode(audio_bytes).decode("utf-8")
|
||||
message = {
|
||||
"type": "input_audio_buffer.append",
|
||||
"audio": audio_b64,
|
||||
}
|
||||
await self.ws.send(json.dumps(message))
|
||||
|
||||
async def commit_audio_buffer(self):
|
||||
"""Commit the audio buffer to trigger processing."""
|
||||
if not self.is_active or not self.ws:
|
||||
return
|
||||
|
||||
message = {"type": "input_audio_buffer.commit"}
|
||||
await self.ws.send(json.dumps(message))
|
||||
|
||||
async def capture_audio(self):
|
||||
"""Capture audio from microphone and send to server."""
|
||||
print("\n🎤 Starting audio capture...")
|
||||
print("Speak into your microphone. Press Ctrl+C to stop.\n")
|
||||
|
||||
self.input_stream = self.pyaudio.open(
|
||||
format=FORMAT,
|
||||
channels=CHANNELS,
|
||||
rate=INPUT_SAMPLE_RATE,
|
||||
input=True,
|
||||
frames_per_buffer=CHUNK_SIZE,
|
||||
)
|
||||
|
||||
try:
|
||||
while self.is_active:
|
||||
audio_data = self.input_stream.read(CHUNK_SIZE, exception_on_overflow=False)
|
||||
await self.send_audio_chunk(audio_data)
|
||||
await asyncio.sleep(0.01) # Small delay to prevent overwhelming
|
||||
except Exception as e:
|
||||
print(f"Error capturing audio: {e}")
|
||||
finally:
|
||||
if self.input_stream:
|
||||
self.input_stream.stop_stream()
|
||||
self.input_stream.close()
|
||||
|
||||
async def play_audio(self):
|
||||
"""Play audio responses from the server."""
|
||||
print("🔊 Starting audio playback...")
|
||||
|
||||
self.output_stream = self.pyaudio.open(
|
||||
format=FORMAT,
|
||||
channels=CHANNELS,
|
||||
rate=OUTPUT_SAMPLE_RATE,
|
||||
output=True,
|
||||
frames_per_buffer=CHUNK_SIZE,
|
||||
)
|
||||
|
||||
try:
|
||||
while self.is_active:
|
||||
try:
|
||||
audio_data = await asyncio.wait_for(
|
||||
self.audio_queue.get(), timeout=0.1
|
||||
)
|
||||
if audio_data:
|
||||
self.output_stream.write(audio_data)
|
||||
except asyncio.TimeoutError:
|
||||
continue
|
||||
except Exception as e:
|
||||
print(f"Error playing audio: {e}")
|
||||
finally:
|
||||
if self.output_stream:
|
||||
self.output_stream.stop_stream()
|
||||
self.output_stream.close()
|
||||
|
||||
async def close(self):
|
||||
"""Close the connection and cleanup."""
|
||||
self.is_active = False
|
||||
|
||||
if self.ws:
|
||||
await self.ws.close()
|
||||
|
||||
if self.input_stream:
|
||||
self.input_stream.stop_stream()
|
||||
self.input_stream.close()
|
||||
|
||||
if self.output_stream:
|
||||
self.output_stream.stop_stream()
|
||||
self.output_stream.close()
|
||||
|
||||
self.pyaudio.terminate()
|
||||
print("\n✓ Connection closed")
|
||||
|
||||
|
||||
async def main():
|
||||
"""Main function to run the realtime client."""
|
||||
print("=" * 80)
|
||||
print("Bedrock Nova Sonic Realtime Client")
|
||||
print("=" * 80)
|
||||
print()
|
||||
|
||||
client = RealtimeClient(LITELLM_PROXY_URL, LITELLM_API_KEY)
|
||||
|
||||
try:
|
||||
# Connect to server
|
||||
await client.connect()
|
||||
|
||||
# Send session configuration
|
||||
await client.send_session_update()
|
||||
|
||||
# Wait a moment for session to be established
|
||||
await asyncio.sleep(0.5)
|
||||
|
||||
# Start tasks
|
||||
receive_task = asyncio.create_task(client.receive_messages())
|
||||
capture_task = asyncio.create_task(client.capture_audio())
|
||||
playback_task = asyncio.create_task(client.play_audio())
|
||||
|
||||
# Wait for user to interrupt
|
||||
await asyncio.gather(
|
||||
receive_task,
|
||||
capture_task,
|
||||
playback_task,
|
||||
return_exceptions=True,
|
||||
)
|
||||
|
||||
except KeyboardInterrupt:
|
||||
print("\n\n⚠ Interrupted by user")
|
||||
except Exception as e:
|
||||
print(f"\n❌ Error: {e}")
|
||||
import traceback
|
||||
traceback.print_exc()
|
||||
finally:
|
||||
await client.close()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
print("\nMake sure:")
|
||||
print("1. LiteLLM proxy is running on port 4000")
|
||||
print("2. Bedrock is configured in proxy_server_config.yaml")
|
||||
print("3. AWS credentials are set")
|
||||
print()
|
||||
|
||||
try:
|
||||
asyncio.run(main())
|
||||
except KeyboardInterrupt:
|
||||
print("\n\nGoodbye!")
|
||||
|
|
@ -5,7 +5,8 @@ FROM ghcr.io/berriai/litellm:litellm_fwd_server_root_path-dev
|
|||
WORKDIR /app
|
||||
|
||||
# Install Node.js and npm (adjust version as needed)
|
||||
RUN apt-get update && apt-get install -y nodejs npm
|
||||
RUN apt-get update && apt-get install -y nodejs npm && \
|
||||
npm install -g npm@latest tar@latest
|
||||
|
||||
# Copy the UI source into the container
|
||||
COPY ./ui/litellm-dashboard /app/ui/litellm-dashboard
|
||||
|
|
|
|||
|
|
@ -49,7 +49,8 @@ FROM $LITELLM_RUNTIME_IMAGE AS runtime
|
|||
USER root
|
||||
|
||||
# Install runtime dependencies
|
||||
RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip libsndfile
|
||||
RUN apk add --no-cache bash openssl tzdata nodejs npm python3 py3-pip libsndfile && \
|
||||
npm install -g npm@latest tar@latest
|
||||
|
||||
WORKDIR /app
|
||||
# Copy the current directory contents into the container at /app
|
||||
|
|
|
|||
|
|
@ -61,7 +61,8 @@ RUN apt-get update && apt-get install -y --no-install-recommends \
|
|||
libatomic1 \
|
||||
nodejs \
|
||||
npm \
|
||||
&& rm -rf /var/lib/apt/lists/*
|
||||
&& rm -rf /var/lib/apt/lists/* \
|
||||
&& npm install -g npm@latest tar@latest
|
||||
|
||||
WORKDIR /app
|
||||
|
||||
|
|
|
|||
|
|
@ -104,7 +104,8 @@ RUN for i in 1 2 3; do \
|
|||
done \
|
||||
&& for i in 1 2 3; do \
|
||||
apk add --no-cache python3 py3-pip bash openssl tzdata nodejs npm supervisor && break || sleep 5; \
|
||||
done
|
||||
done \
|
||||
&& npm install -g npm@latest tar@latest
|
||||
|
||||
# Copy artifacts from builder
|
||||
COPY --from=builder /app/requirements.txt /app/requirements.txt
|
||||
|
|
|
|||
|
|
@ -15,6 +15,7 @@ authors:
|
|||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
description: "Guide to Claude Opus 4.5 and advanced features in LiteLLM: Tool Search, Programmatic Tool Calling, and Effort Parameter."
|
||||
tags: [anthropic, claude, tool search, programmatic tool calling, effort, advanced features]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
|
|
|||
|
|
@ -15,6 +15,7 @@ authors:
|
|||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
description: "Common questions and best practices for using gemini-3-pro-preview with LiteLLM Proxy and SDK."
|
||||
tags: [gemini, day 0 support, llms]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
|
|
|||
|
|
@ -15,6 +15,7 @@ authors:
|
|||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
description: "Guide to using Gemini 3 Flash on LiteLLM Proxy and SDK with day 0 support."
|
||||
tags: [gemini, day 0 support, llms]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
|
|
|||
|
|
@ -74,6 +74,18 @@ You can find [supported data regions litellm here](../docs/data_security#support
|
|||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How to set up and verify your Enterprise License
|
||||
|
||||
1. Add your license key to the environment:
|
||||
|
||||
```env
|
||||
LITELLM_LICENSE="eyJ..."
|
||||
```
|
||||
|
||||
2. Restart LiteLLM Proxy.
|
||||
|
||||
3. Open `http://<your-proxy-host>:<port>/` — the Swagger page should show **"Enterprise Edition"** in the description. If it doesn't, check that the key is correct, unexpired, and that the proxy was fully restarted.
|
||||
|
||||
### SLA's + Professional Support
|
||||
|
||||
Professional Support can assist with LLM/Provider integrations, deployment, upgrade management, and LLM Provider troubleshooting. We can’t solve your own infrastructure-related issues but we will guide you to fix them.
|
||||
|
|
|
|||
|
|
@ -1,5 +1,8 @@
|
|||
# Sarvam.ai
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
LiteLLM supports all the text models from [Sarvam ai](https://docs.sarvam.ai/api-reference-docs/chat/chat-completions)
|
||||
|
||||
## Usage
|
||||
|
|
|
|||
|
|
@ -312,6 +312,7 @@ Gemini models with audio output capabilities using the chat completions API.
|
|||
- Only supports `pcm16` audio format
|
||||
- Streaming not yet supported
|
||||
- Must set `modalities: ["audio"]`
|
||||
- When using via LiteLLM Proxy, must include `"allowed_openai_params": ["audio", "modalities"]` in the request body to enable audio parameters
|
||||
:::
|
||||
|
||||
### Quick Start
|
||||
|
|
@ -372,7 +373,8 @@ curl http://0.0.0.0:4000/v1/chat/completions \
|
|||
"model": "gemini-tts",
|
||||
"messages": [{"role": "user", "content": "Say hello in a friendly voice"}],
|
||||
"modalities": ["audio"],
|
||||
"audio": {"voice": "Kore", "format": "pcm16"}
|
||||
"audio": {"voice": "Kore", "format": "pcm16"},
|
||||
"allowed_openai_params": ["audio", "modalities"]
|
||||
}'
|
||||
```
|
||||
|
||||
|
|
@ -389,6 +391,7 @@ response = client.chat.completions.create(
|
|||
messages=[{"role": "user", "content": "Say hello in a friendly voice"}],
|
||||
modalities=["audio"],
|
||||
audio={"voice": "Kore", "format": "pcm16"},
|
||||
extra_body={"allowed_openai_params": ["audio", "modalities"]}
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
|
|
|||
|
|
@ -321,6 +321,7 @@ router_settings:
|
|||
| redis_host | string | The host address for the Redis server. **Only set this if you have multiple instances of LiteLLM Proxy and want current tpm/rpm tracking to be shared across them** |
|
||||
| redis_password | string | The password for the Redis server. **Only set this if you have multiple instances of LiteLLM Proxy and want current tpm/rpm tracking to be shared across them** |
|
||||
| redis_port | string | The port number for the Redis server. **Only set this if you have multiple instances of LiteLLM Proxy and want current tpm/rpm tracking to be shared across them**|
|
||||
| redis_db | int | The database number for the Redis server. **Only set this if you have multiple instances of LiteLLM Proxy and want current tpm/rpm tracking to be shared across them**|
|
||||
| enable_pre_call_check | boolean | If true, checks if a call is within the model's context window before making the call. [More information here](reliability) |
|
||||
| content_policy_fallbacks | array of objects | Specifies fallback models for content policy violations. [More information here](reliability) |
|
||||
| fallbacks | array of objects | Specifies fallback models for all types of errors. [More information here](reliability) |
|
||||
|
|
@ -507,6 +508,7 @@ router_settings:
|
|||
| DD_AGENT_HOST | Hostname or IP of DataDog agent (e.g., "localhost"). When set, logs are sent to agent instead of direct API
|
||||
| DD_AGENT_PORT | Port of DataDog agent for log intake. Default is 10518
|
||||
| DD_API_KEY | API key for Datadog integration
|
||||
| DD_APP_KEY | Application key for Datadog Cost Management integration. Required along with DD_API_KEY for cost metrics
|
||||
| DD_SITE | Site URL for Datadog (e.g., datadoghq.com)
|
||||
| DD_SOURCE | Source identifier for Datadog logs
|
||||
| DD_TRACER_STREAMING_CHUNK_YIELD_RESOURCE | Resource name for Datadog tracing of streaming chunk yields. Default is "streaming.chunk.yield"
|
||||
|
|
@ -643,6 +645,10 @@ router_settings:
|
|||
| GENERIC_USERINFO_ENDPOINT | Endpoint to fetch user information in generic OAuth
|
||||
| GENERIC_LOGGER_ENDPOINT | Endpoint URL for the Generic Logger callback to send logs to
|
||||
| GENERIC_LOGGER_HEADERS | JSON string of headers to include in Generic Logger callback requests
|
||||
| GENERIC_ROLE_MAPPINGS_DEFAULT_ROLE | Default LiteLLM role to assign when no role mapping matches in generic SSO. Used with GENERIC_ROLE_MAPPINGS_ROLES
|
||||
| GENERIC_ROLE_MAPPINGS_GROUP_CLAIM | The claim/attribute name in the SSO token that contains the user's groups. Used for role mapping
|
||||
| GENERIC_ROLE_MAPPINGS_ROLES | Python dict string mapping LiteLLM roles to SSO group names. Example: `{"proxy_admin": ["admin-group"], "internal_user": ["users"]}`
|
||||
| GENERIC_USER_ROLE_MAPPINGS | Alternative to GENERIC_ROLE_MAPPINGS_ROLES for configuring user role mappings from SSO
|
||||
| GEMINI_API_BASE | Base URL for Gemini API. Default is https://generativelanguage.googleapis.com
|
||||
| GALILEO_BASE_URL | Base URL for Galileo platform
|
||||
| GALILEO_PASSWORD | Password for Galileo authentication
|
||||
|
|
@ -735,6 +741,7 @@ router_settings:
|
|||
| LITELLM_CLI_JWT_EXPIRATION_HOURS | Expiration time in hours for CLI-generated JWT tokens. Default is 24 hours
|
||||
| LITELLM_DD_AGENT_HOST | Hostname or IP of DataDog agent for LiteLLM-specific logging. When set, logs are sent to agent instead of direct API
|
||||
| LITELLM_DD_AGENT_PORT | Port of DataDog agent for LiteLLM-specific log intake. Default is 10518
|
||||
| LITELLM_DD_LLM_OBS_PORT | Port for Datadog LLM Observability agent. Default is 8126
|
||||
| LITELLM_DONT_SHOW_FEEDBACK_BOX | Flag to hide feedback box in LiteLLM UI
|
||||
| LITELLM_DROP_PARAMS | Parameters to drop in LiteLLM requests
|
||||
| LITELLM_MODIFY_PARAMS | Parameters to modify in LiteLLM requests
|
||||
|
|
@ -830,6 +837,7 @@ router_settings:
|
|||
| OPENMETER_EVENT_TYPE | Type of events sent to OpenMeter
|
||||
| ONYX_API_BASE | Base URL for Onyx Security AI Guard service (defaults to https://ai-guard.onyx.security)
|
||||
| ONYX_API_KEY | API key for Onyx Security AI Guard service
|
||||
| ONYX_TIMEOUT | Timeout in seconds for Onyx Guard server requests. Default is 10
|
||||
| OTEL_ENDPOINT | OpenTelemetry endpoint for traces
|
||||
| OTEL_EXPORTER_OTLP_ENDPOINT | OpenTelemetry endpoint for traces
|
||||
| OTEL_ENVIRONMENT_NAME | Environment name for OpenTelemetry
|
||||
|
|
@ -892,6 +900,8 @@ router_settings:
|
|||
| ROUTER_MAX_FALLBACKS | Maximum number of fallbacks for router. Default is 5
|
||||
| RUNWAYML_DEFAULT_API_VERSION | Default API version for RunwayML service. Default is "2024-11-06"
|
||||
| RUNWAYML_POLLING_TIMEOUT | Timeout in seconds for RunwayML image generation polling. Default is 600 (10 minutes)
|
||||
| S3_VECTORS_DEFAULT_DIMENSION | Default vector dimension for S3 Vectors RAG ingestion. Default is 1024
|
||||
| S3_VECTORS_DEFAULT_DISTANCE_METRIC | Default distance metric for S3 Vectors RAG ingestion. Options: "cosine", "euclidean". Default is "cosine"
|
||||
| SECRET_MANAGER_REFRESH_INTERVAL | Refresh interval in seconds for secret manager. Default is 86400 (24 hours)
|
||||
| SEPARATE_HEALTH_APP | If set to '1', runs health endpoints on a separate ASGI app and port. Default: '0'.
|
||||
| SEPARATE_HEALTH_PORT | Port for the separate health endpoints app. Only used if SEPARATE_HEALTH_APP=1. Default: 4001.
|
||||
|
|
|
|||
|
|
@ -9,6 +9,7 @@ LiteLLM provides flexible cost tracking and pricing customization for all LLM pr
|
|||
- **Custom Pricing** - Override default model costs or set pricing for custom models
|
||||
- **Cost Per Token** - Track costs based on input/output tokens (most common)
|
||||
- **Cost Per Second** - Track costs based on runtime (e.g., Sagemaker)
|
||||
- **Zero-Cost Models** - Bypass budget checks for free/on-premises models by setting costs to 0
|
||||
- **[Provider Discounts](./provider_discounts.md)** - Apply percentage-based discounts to specific providers
|
||||
- **[Provider Margins](./provider_margins.md)** - Add fees/margins to LLM costs for internal billing
|
||||
- **Base Model Mapping** - Ensure accurate cost tracking for Azure deployments
|
||||
|
|
@ -106,6 +107,51 @@ There are other keys you can use to specify costs for different scenarios and mo
|
|||
|
||||
These keys evolve based on how new models handle multimodality. The latest version can be found at [https://github.com/BerriAI/litellm/blob/main/model_prices_and_context_window.json](https://github.com/BerriAI/litellm/blob/main/model_prices_and_context_window.json).
|
||||
|
||||
## Zero-Cost Models (Bypass Budget Checks)
|
||||
|
||||
**Use Case**: You have on-premises or free models that should be accessible even when users exceed their budget limits.
|
||||
|
||||
**Solution** ✅: Set both `input_cost_per_token` and `output_cost_per_token` to `0` (explicitly) to bypass all budget checks for that model.
|
||||
|
||||
:::info
|
||||
|
||||
When a model is configured with zero cost, LiteLLM will automatically skip ALL budget checks (user, team, team member, end-user, organization, and global proxy budget) for requests to that model.
|
||||
|
||||
**Important**: Both costs must be **explicitly set to 0**. If costs are `null` or undefined, the model will be treated as having cost and budget checks will apply.
|
||||
|
||||
:::
|
||||
|
||||
### Configuration Example
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
# On-premises model - free to use
|
||||
- model_name: on-prem-llama
|
||||
litellm_params:
|
||||
model: ollama/llama3
|
||||
api_base: http://localhost:11434
|
||||
model_info:
|
||||
input_cost_per_token: 0 # 👈 Explicitly set to 0
|
||||
output_cost_per_token: 0 # 👈 Explicitly set to 0
|
||||
|
||||
# Paid cloud model - budget checks apply
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
# No model_info - uses default pricing from cost map
|
||||
```
|
||||
|
||||
### Behavior
|
||||
|
||||
With the above configuration:
|
||||
|
||||
- **User over budget** → Can still use `on-prem-llama` ✅, but blocked from `gpt-4` ❌
|
||||
- **Team over budget** → Can still use `on-prem-llama` ✅, but blocked from `gpt-4` ❌
|
||||
- **End-user over budget** → Can still use `on-prem-llama` ✅, but blocked from `gpt-4` ❌
|
||||
|
||||
This ensures your free/on-premises models remain accessible regardless of budget constraints, while paid models are still properly governed.
|
||||
|
||||
## Set 'base_model' for Cost Tracking (e.g. Azure deployments)
|
||||
|
||||
**Problem**: Azure returns `gpt-4` in the response when `azure/gpt-4-1106-preview` is used. This leads to inaccurate cost tracking
|
||||
|
|
|
|||
|
|
@ -6,6 +6,16 @@ import TabItem from '@theme/TabItem';
|
|||
|
||||
See supported Embedding Providers & Models [here](https://docs.litellm.ai/docs/embedding/supported_embedding)
|
||||
|
||||
## Supported Input Formats
|
||||
|
||||
The `/v1/embeddings` endpoint follows the [OpenAI embeddings API specification](https://platform.openai.com/docs/api-reference/embeddings/create). The following input formats are supported:
|
||||
|
||||
| Format | Example |
|
||||
|--------|---------|
|
||||
| String | `"input": "Hello"` |
|
||||
| Array of strings | `"input": ["Hello", "World"]` |
|
||||
| Array of tokens (integers) | `"input": [1234, 5678, 9012]` |
|
||||
| Array of token arrays | `"input": [[1234, 5678], [9012, 3456]]` |
|
||||
|
||||
## Quick start
|
||||
Here's how to route between GPT-J embedding (sagemaker endpoint), Amazon Titan embedding (Bedrock) and Azure OpenAI embedding on the proxy server:
|
||||
|
|
|
|||
|
|
@ -69,6 +69,67 @@ router_settings:
|
|||
redis_port: 1992
|
||||
```
|
||||
|
||||
## Enforce Model Rate Limits
|
||||
|
||||
Strictly enforce RPM/TPM limits set on deployments. When limits are exceeded, requests are blocked **before** reaching the LLM provider with a `429 Too Many Requests` error.
|
||||
|
||||
:::info
|
||||
By default, `rpm` and `tpm` values are only used for **routing decisions** (picking deployments with capacity). With `enforce_model_rate_limits`, they become **hard limits**.
|
||||
:::
|
||||
|
||||
### Quick Start
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: openai/gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
rpm: 60 # 60 requests per minute
|
||||
tpm: 90000 # 90k tokens per minute
|
||||
|
||||
router_settings:
|
||||
optional_pre_call_checks:
|
||||
- enforce_model_rate_limits # 👈 Enables strict enforcement
|
||||
```
|
||||
|
||||
### How It Works
|
||||
|
||||
| Limit Type | Enforcement | Accuracy |
|
||||
|------------|-------------|----------|
|
||||
| **RPM** | Hard limit - blocked at exact threshold | 100% accurate |
|
||||
| **TPM** | Best-effort - may slightly exceed | Blocked when already over limit |
|
||||
|
||||
**Why TPM is best-effort:** Token count is unknown until the LLM responds. TPM is checked before each request (blocks if already over), and tracked after (adds actual tokens used).
|
||||
|
||||
### Error Response
|
||||
|
||||
```json
|
||||
{
|
||||
"error": {
|
||||
"message": "Model rate limit exceeded. RPM limit=60, current usage=60",
|
||||
"type": "rate_limit_error",
|
||||
"code": 429
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Response includes `retry-after: 60` header.
|
||||
|
||||
### Multi-Instance Deployment
|
||||
|
||||
For multiple LiteLLM proxy instances, add Redis to share rate limit state:
|
||||
|
||||
```yaml
|
||||
router_settings:
|
||||
optional_pre_call_checks:
|
||||
- enforce_model_rate_limits
|
||||
redis_host: redis.example.com
|
||||
redis_port: 6379
|
||||
redis_password: your-password
|
||||
```
|
||||
|
||||
|
||||
:::info
|
||||
Detailed information about [routing strategies can be found here](../routing)
|
||||
:::
|
||||
|
|
|
|||
58
docs/my-website/docs/proxy/request_tags.md
Normal file
58
docs/my-website/docs/proxy/request_tags.md
Normal file
|
|
@ -0,0 +1,58 @@
|
|||
# Request Tags for Spend Tracking
|
||||
|
||||
Add tags to model deployments to track spend by environment, AWS account, or any custom label.
|
||||
|
||||
Tags appear in the `request_tags` field of LiteLLM spend logs.
|
||||
|
||||
## Config Setup
|
||||
|
||||
Set tags on model deployments in `config.yaml`:
|
||||
|
||||
```yaml title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: azure/gpt-4-prod
|
||||
api_key: os.environ/AZURE_PROD_API_KEY
|
||||
api_base: https://prod.openai.azure.com/
|
||||
tags: ["AWS_IAM_PROD"] # 👈 Tag for production
|
||||
|
||||
- model_name: gpt-4-dev
|
||||
litellm_params:
|
||||
model: azure/gpt-4-dev
|
||||
api_key: os.environ/AZURE_DEV_API_KEY
|
||||
api_base: https://dev.openai.azure.com/
|
||||
tags: ["AWS_IAM_DEV"] # 👈 Tag for development
|
||||
```
|
||||
|
||||
## Make Request
|
||||
|
||||
Requests just specify the model - tags are automatically applied:
|
||||
|
||||
```bash
|
||||
curl -X POST 'http://0.0.0.0:4000/chat/completions' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-d '{
|
||||
"model": "gpt-4",
|
||||
"messages": [{"role": "user", "content": "Hello"}]
|
||||
}'
|
||||
```
|
||||
|
||||
## Spend Logs
|
||||
|
||||
The tag from the model config appears in `LiteLLM_SpendLogs`:
|
||||
|
||||
```json
|
||||
{
|
||||
"request_id": "chatcmpl-abc123",
|
||||
"request_tags": ["AWS_IAM_PROD"],
|
||||
"spend": 0.002,
|
||||
"model": "gpt-4"
|
||||
}
|
||||
```
|
||||
|
||||
## Related
|
||||
|
||||
- [Spend Tracking Overview](cost_tracking.md)
|
||||
- [Tag Budgets](tag_budgets.md) - Set budget limits per tag
|
||||
|
|
@ -25,7 +25,10 @@ View Spend, Token Usage, Key, Team Name for Each Request to LiteLLM
|
|||
|
||||
## Tracking - Request / Response Content in Logs Page
|
||||
|
||||
If you want to view request and response content on LiteLLM Logs, you need to opt in with this setting
|
||||
If you want to view request and response content on LiteLLM Logs, you can enable it in either place:
|
||||
|
||||
- **From the UI (no restart):** Use [UI Spend Log Settings](./ui_spend_log_settings.md) — open Logs → Settings → enable "Store Prompts in Spend Logs" → Save. Takes effect immediately and overrides config.
|
||||
- **From config:** Add this to your `proxy_config.yaml` (requires restart):
|
||||
|
||||
```yaml
|
||||
general_settings:
|
||||
|
|
@ -57,7 +60,10 @@ general_settings:
|
|||
|
||||
If you're storing spend logs, it might be a good idea to delete them regularly to keep the database fast.
|
||||
|
||||
LiteLLM lets you configure this in your `proxy_config.yaml`:
|
||||
You can set the retention period in either place:
|
||||
|
||||
- **From the UI (no restart):** [UI Spend Log Settings](./ui_spend_log_settings.md) — Logs → Settings → set Retention Period → Save.
|
||||
- **From config:** Add the following to your `proxy_config.yaml` (requires restart):
|
||||
|
||||
```yaml
|
||||
general_settings:
|
||||
|
|
|
|||
92
docs/my-website/docs/proxy/ui_spend_log_settings.md
Normal file
92
docs/my-website/docs/proxy/ui_spend_log_settings.md
Normal file
|
|
@ -0,0 +1,92 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
# UI Spend Log Settings
|
||||
|
||||
Configure spend log behavior directly from the Admin UI—no config file edits or proxy restart required. This is especially useful for cloud deployments where updating the config is difficult or requires a long release process.
|
||||
|
||||
## Overview
|
||||
|
||||
Previously, spend log options (such as storing request/response content and retention period) had to be set in `proxy_config.yaml` under `general_settings`. Changing them required editing the config and restarting the proxy, which was a pain point for users-especially in cloud environments—who don't have easy access to the config or whose deployment process makes config updates slow.
|
||||
|
||||
<Image img={require('../../img/ui_spend_logs_settings.png')} />
|
||||
|
||||
**UI Spend Log Settings** lets you:
|
||||
|
||||
- **Store prompts in spend logs** – Enable or disable storing request and response content in the spend logs table (only affects logs created after you change the setting)
|
||||
- **Set retention period** – Configure how long spend logs are kept before automatic cleanup (e.g. `7d`, `30d`)
|
||||
- **Apply changes immediately** – No proxy restart needed; settings take effect for new requests as soon as you save
|
||||
|
||||
:::warning UI overrides config
|
||||
Settings changed in the UI **override** the values in your config file. For example, if `store_prompts_in_spend_logs` is explicitly set to `false` in `general_settings`, turning it on in the UI will still enable storing prompts. Use the UI when you want runtime control without redeploying.
|
||||
:::
|
||||
|
||||
## Settings You Can Configure
|
||||
|
||||
| Setting | Description |
|
||||
| ------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
|
||||
| **Store Prompts in Spend Logs** | When enabled, request messages and response content are stored for **new** spend logs so you can view them in the Logs UI. Logs created before you enabled this will not have request/response content. When disabled, only metadata (e.g. tokens, cost, model) is stored for new logs. |
|
||||
| **Retention Period** | Maximum time to keep spend logs before they are automatically deleted (e.g. `7d`, `30d`). Optional; if not set, logs are retained according to your config or default behavior. |
|
||||
|
||||
The same options can be set in config via [general_settings](./config_settings.md#general_settings---reference) (`store_prompts_in_spend_logs`, `maximum_spend_logs_retention_period`). Values set in the UI take precedence.
|
||||
|
||||
## How to Configure Spend Log Settings in the UI
|
||||
|
||||
### 1. Open the Logs page
|
||||
|
||||
Navigate to the Admin UI (e.g. `http://localhost:4000/ui` or your `PROXY_BASE_URL/ui`) and click **Logs**.
|
||||
|
||||
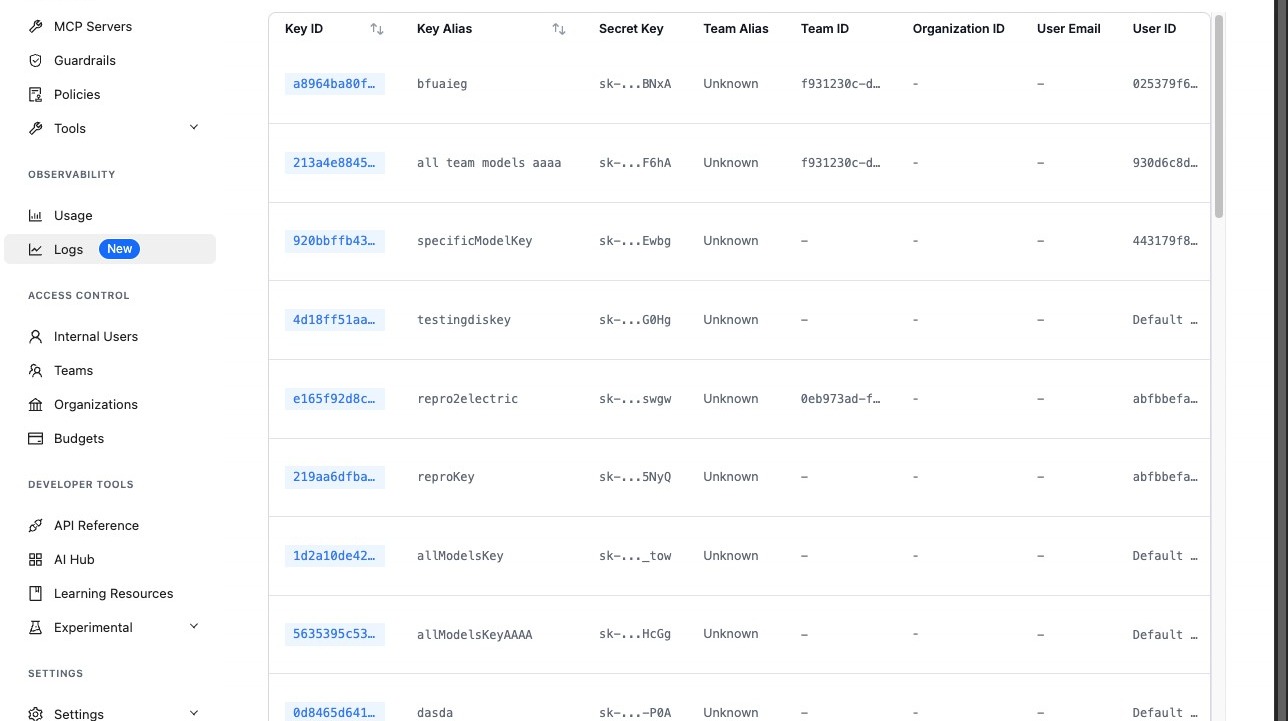
|
||||
|
||||
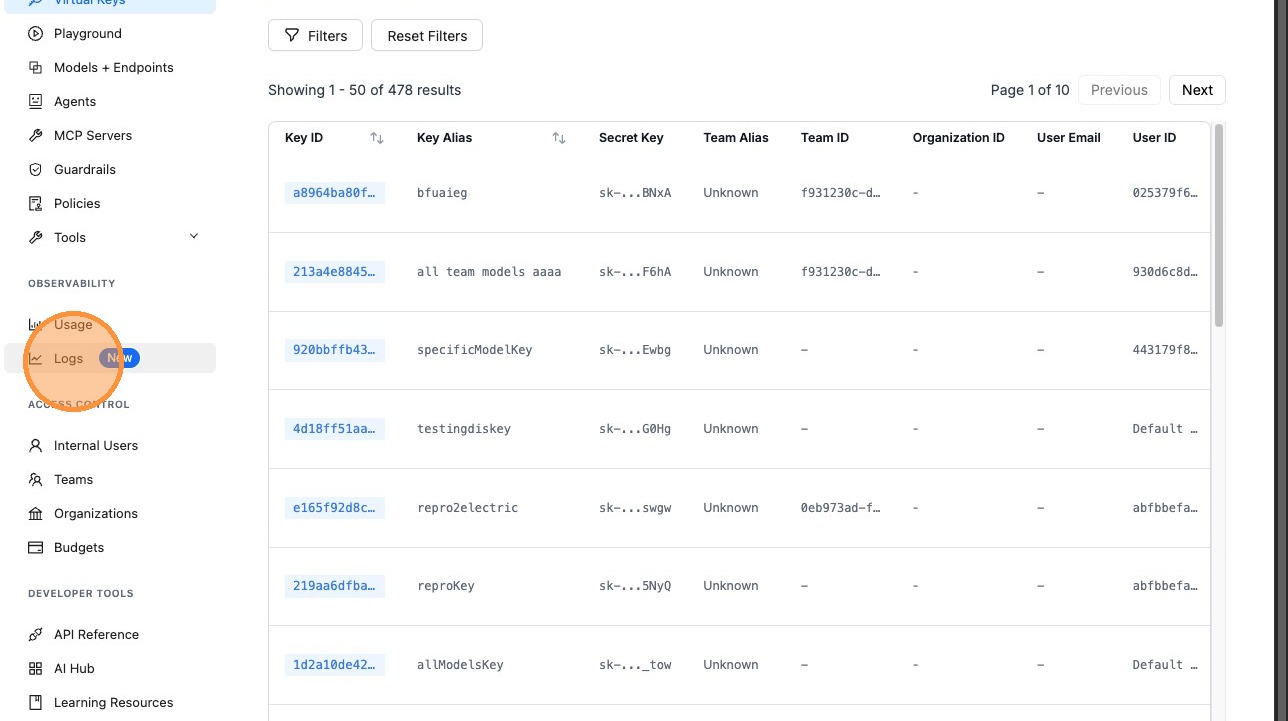
|
||||
|
||||
### 2. Open Logs settings
|
||||
|
||||
Click the **Settings** (gear) icon on the Logs page to open the spend log settings panel.
|
||||
|
||||
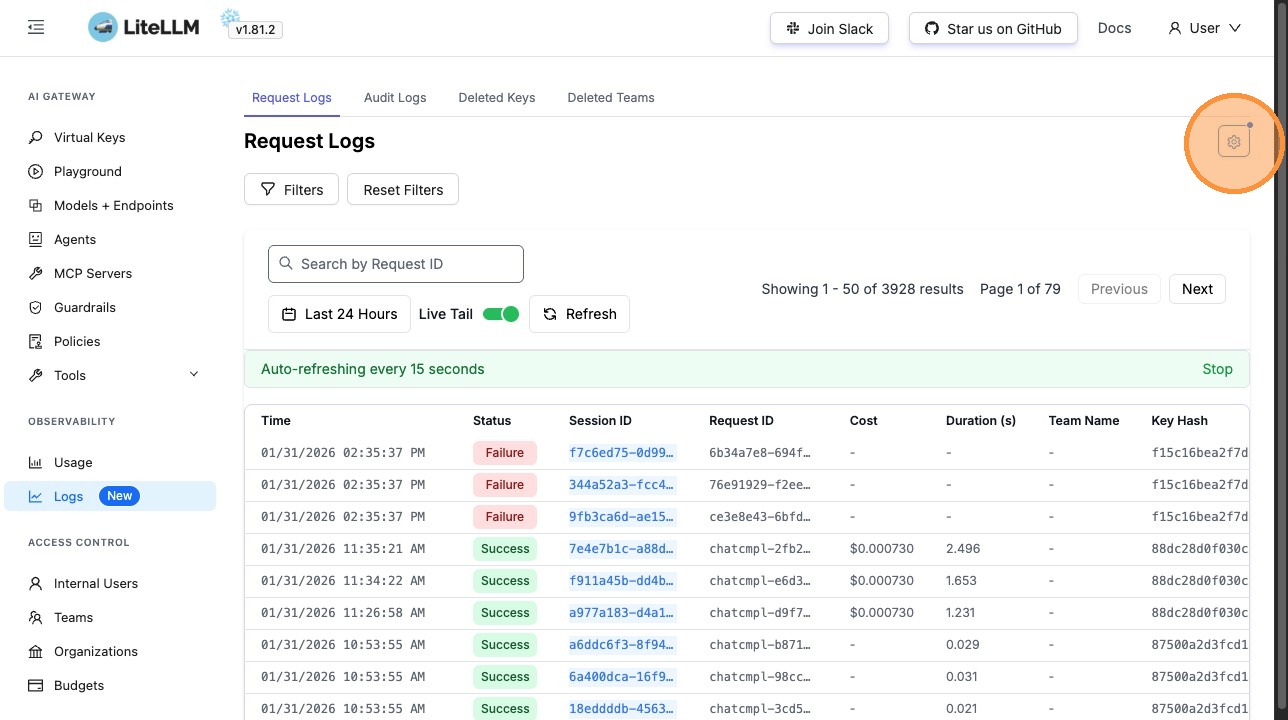
|
||||
|
||||
### 3. Enable Store Prompts in Spend Logs (optional)
|
||||
|
||||
Turn on **Store Prompts in Spend Logs** if you want request and response content to be stored for new requests and visible when you open those log entries. This only affects logs created after you enable it; existing logs will not gain request/response content. Leave it off if you only need metadata (tokens, cost, model, etc.).
|
||||
|
||||
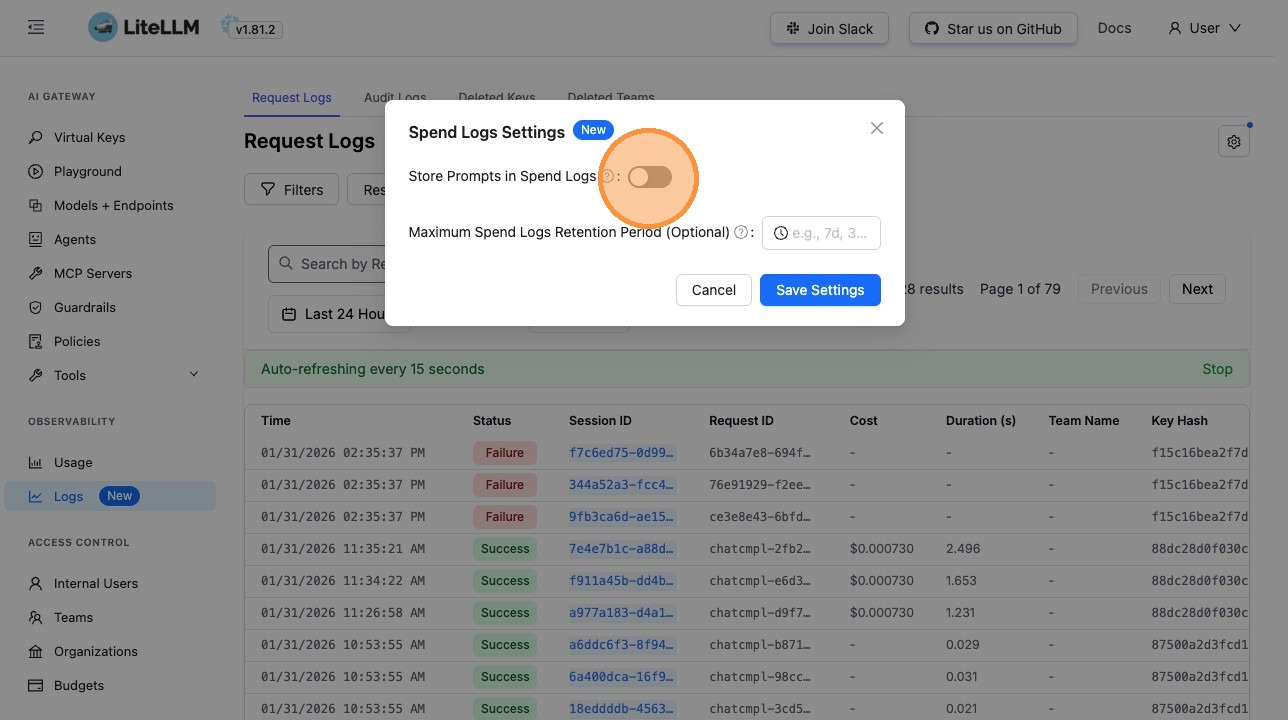
|
||||
|
||||
### 4. Set the retention period (optional)
|
||||
|
||||
Optionally set the **Retention Period** (e.g. `7d`, `30d`) to control how long spend logs are kept before automatic cleanup. Uses the same format as the config option `maximum_spend_logs_retention_period`.
|
||||
|
||||
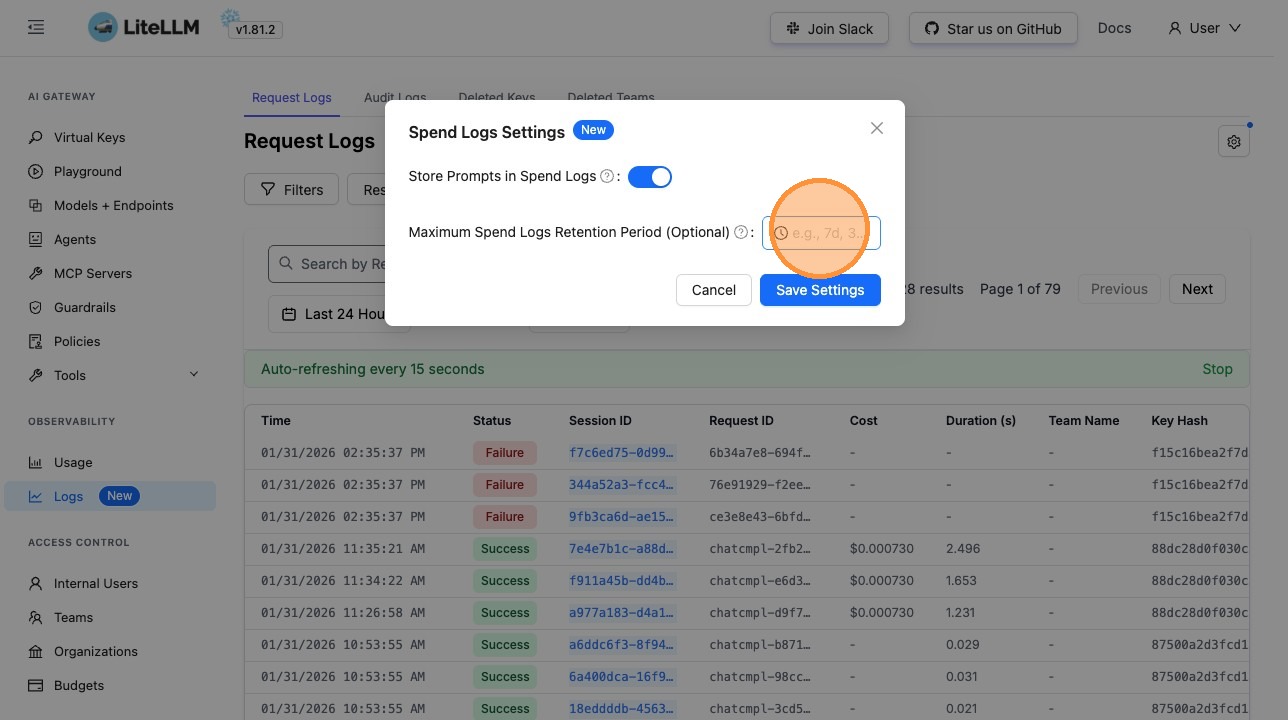
|
||||
|
||||
### 5. Save settings
|
||||
|
||||
Click **Save Settings**. Changes take effect immediately for new requests; no proxy restart is required. Existing logs are not updated.
|
||||
|
||||
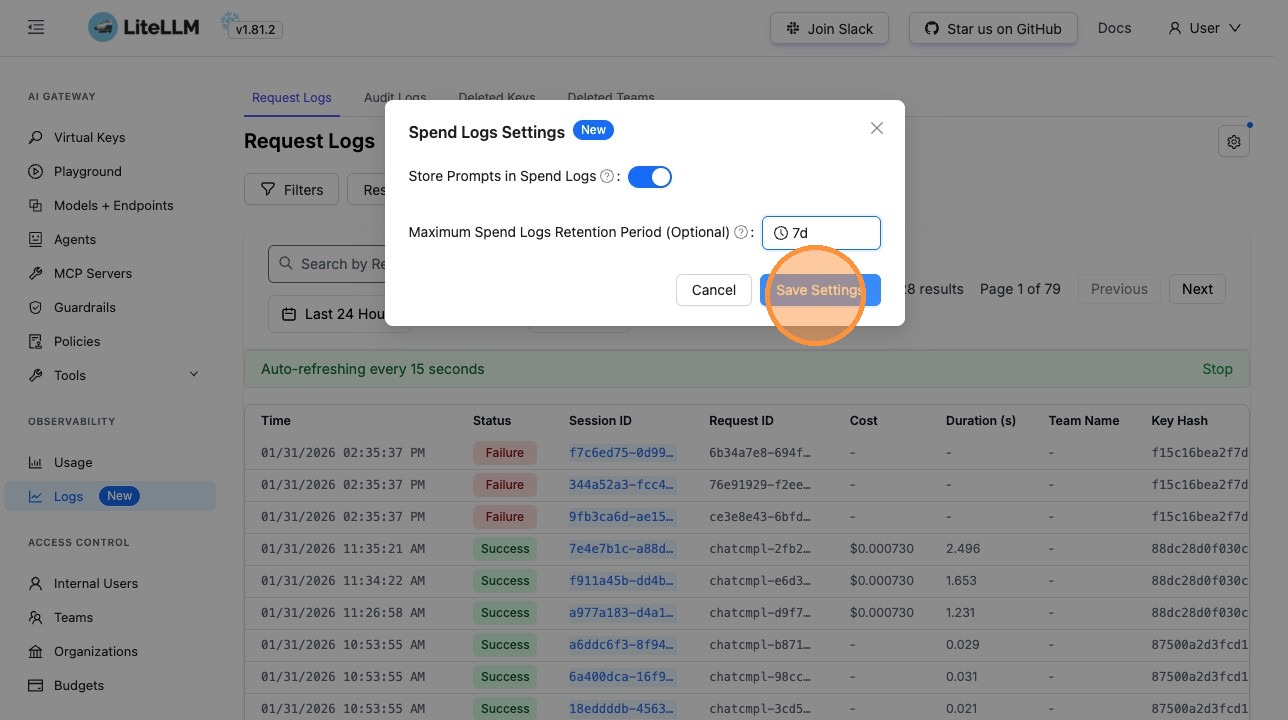
|
||||
|
||||
### 6. Verify: view request and response in a log
|
||||
|
||||
After enabling **Store Prompts in Spend Logs**, make a new request through the proxy, then open that log entry (or any other log created after you enabled the setting). The log details view will include the request and response content. Logs that existed before you turned the setting on will not have this content.
|
||||
|
||||
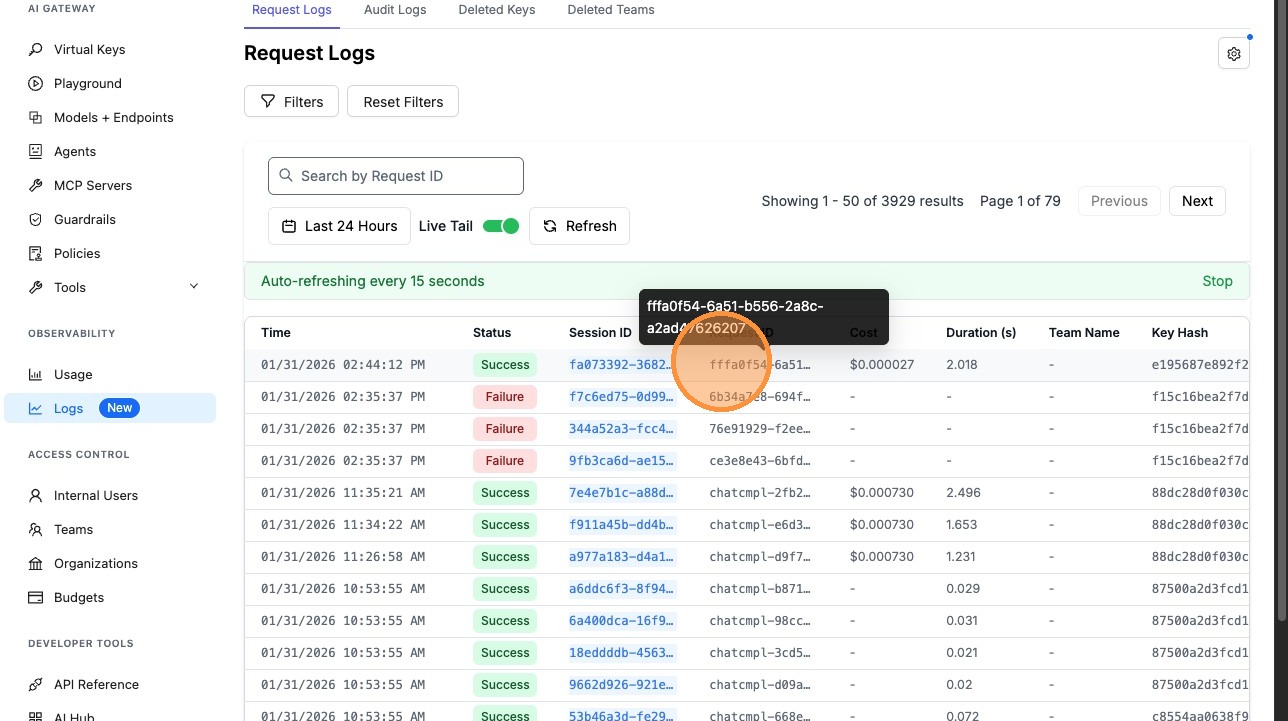
|
||||
|
||||
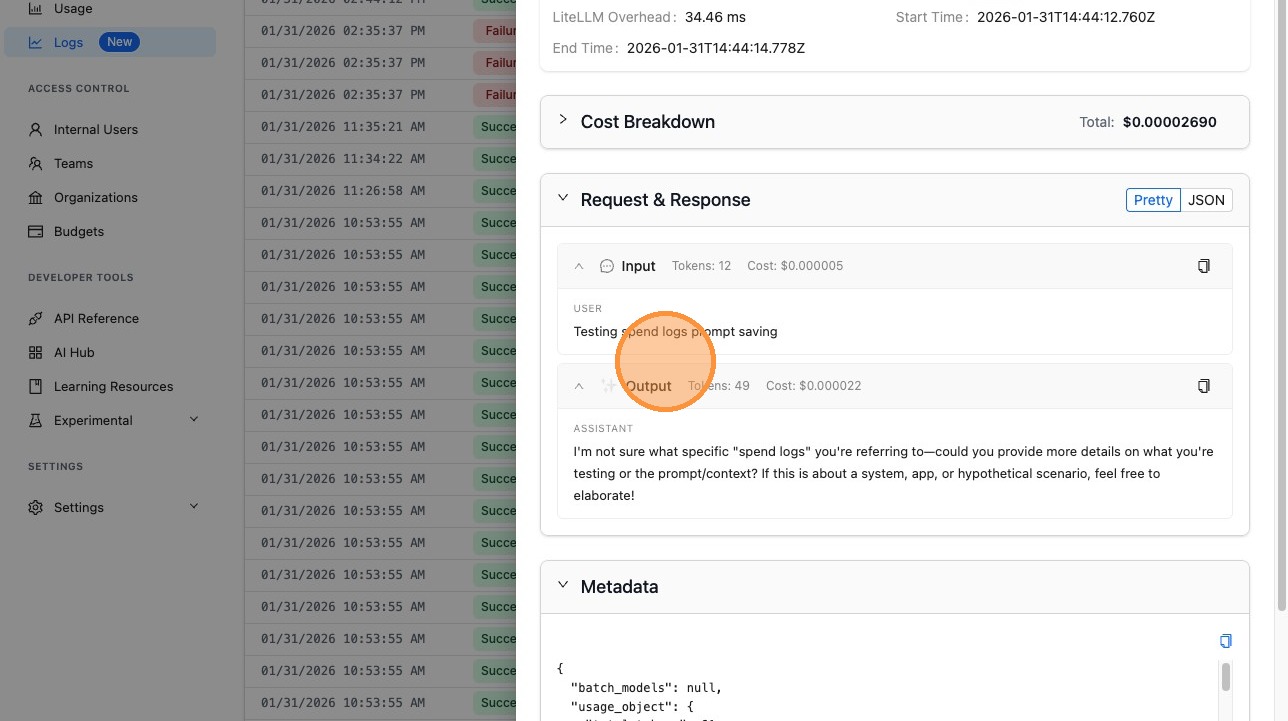
|
||||
|
||||
## Use Cases
|
||||
|
||||
### Cloud and managed deployments
|
||||
|
||||
When the proxy runs in a managed or cloud environment, config may be in a separate repo, require a long release, or be controlled by another team. Using the UI lets you change spend log behavior (e.g. enable prompt storage for debugging or set retention) without going through that process.
|
||||
|
||||
### Quick toggles for debugging
|
||||
|
||||
Temporarily enable **Store Prompts in Spend Logs** to inspect request/response content on new requests when debugging, then turn it off again from the UI without editing config or restarting. Only logs created while the setting was on will contain the content.
|
||||
|
||||
### Retention without redeploying
|
||||
|
||||
Adjust how long spend logs are retained (e.g. shorten to reduce storage or extend for compliance) and have the new retention period and cleanup job take effect immediately.
|
||||
|
||||
## Related Documentation
|
||||
|
||||
- [Getting Started with UI Logs](./ui_logs.md) – Overview of what gets logged and config-based options
|
||||
- [Config Settings](./config_settings.md) – `store_prompts_in_spend_logs`, `disable_spend_logs`, `maximum_spend_logs_retention_period` in `general_settings`
|
||||
- [Spend Logs Deletion](./spend_logs_deletion.md) – How retention and cleanup work
|
||||
|
|
@ -10,6 +10,7 @@ Supported Providers:
|
|||
- Azure
|
||||
- Google AI Studio (Gemini)
|
||||
- Vertex AI
|
||||
- Bedrock
|
||||
|
||||
## Proxy Usage
|
||||
|
||||
|
|
|
|||
|
|
@ -1588,11 +1588,13 @@ Get a slack webhook url from https://api.slack.com/messaging/webhooks
|
|||
Initialize an `AlertingConfig` and pass it to `litellm.Router`. The following code will trigger an alert because `api_key=bad-key` which is invalid
|
||||
|
||||
```python
|
||||
from litellm.router import AlertingConfig
|
||||
import litellm
|
||||
from litellm.router import Router
|
||||
from litellm.types.router import AlertingConfig
|
||||
import os
|
||||
import asyncio
|
||||
|
||||
router = litellm.Router(
|
||||
router = Router(
|
||||
model_list=[
|
||||
{
|
||||
"model_name": "gpt-3.5-turbo",
|
||||
|
|
@ -1603,17 +1605,28 @@ router = litellm.Router(
|
|||
}
|
||||
],
|
||||
alerting_config= AlertingConfig(
|
||||
alerting_threshold=10, # threshold for slow / hanging llm responses (in seconds). Defaults to 300 seconds
|
||||
webhook_url= os.getenv("SLACK_WEBHOOK_URL") # webhook you want to send alerts to
|
||||
alerting_threshold=10,
|
||||
webhook_url= "https:/..."
|
||||
),
|
||||
)
|
||||
try:
|
||||
await router.acompletion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "Hey, how's it going?"}],
|
||||
)
|
||||
except:
|
||||
pass
|
||||
|
||||
async def main():
|
||||
print(f"\n=== Configuration ===")
|
||||
print(f"Slack logger exists: {router.slack_alerting_logger is not None}")
|
||||
|
||||
try:
|
||||
await router.acompletion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "Hey, how's it going?"}],
|
||||
)
|
||||
except Exception as e:
|
||||
print(f"\n=== Exception caught ===")
|
||||
print(f"Waiting 10 seconds for alerts to be sent via periodic flush...")
|
||||
await asyncio.sleep(10)
|
||||
print(f"\n=== After waiting ===")
|
||||
print(f"Alert should have been sent to Slack!")
|
||||
|
||||
asyncio.run(main())
|
||||
```
|
||||
|
||||
## Track cost for Azure Deployments
|
||||
|
|
|
|||
366
docs/my-website/docs/tutorials/bedrock_realtime_with_audio.md
Normal file
366
docs/my-website/docs/tutorials/bedrock_realtime_with_audio.md
Normal file
|
|
@ -0,0 +1,366 @@
|
|||
# Call Bedrock Nova Sonic Realtime API with Audio Input/Output
|
||||
|
||||
:::info
|
||||
Requires LiteLLM Proxy v1.70.1+
|
||||
:::
|
||||
|
||||
## Overview
|
||||
|
||||
Amazon Bedrock's Nova Sonic model supports real-time bidirectional audio streaming for voice conversations. This tutorial shows how to use it through LiteLLM Proxy.
|
||||
|
||||
## Setup
|
||||
|
||||
### 1. Configure LiteLLM Proxy
|
||||
|
||||
Create a `config.yaml` file:
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: "bedrock-sonic"
|
||||
litellm_params:
|
||||
model: bedrock/amazon.nova-sonic-v1:0
|
||||
aws_region_name: us-east-1 # or your preferred region
|
||||
model_info:
|
||||
mode: realtime
|
||||
```
|
||||
|
||||
### 2. Start LiteLLM Proxy
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
## Basic Text Interaction
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
import websockets
|
||||
import json
|
||||
|
||||
LITELLM_API_KEY = "sk-1234" # Your LiteLLM API key
|
||||
LITELLM_URL = 'ws://localhost:4000/v1/realtime?model=bedrock-sonic'
|
||||
|
||||
async def test_text_conversation():
|
||||
async with websockets.connect(
|
||||
LITELLM_URL,
|
||||
additional_headers={
|
||||
"Authorization": f"Bearer {LITELLM_API_KEY}"
|
||||
}
|
||||
) as ws:
|
||||
# Wait for session.created
|
||||
response = await ws.recv()
|
||||
print(f"Connected: {json.loads(response)['type']}")
|
||||
|
||||
# Configure session
|
||||
session_update = {
|
||||
"type": "session.update",
|
||||
"session": {
|
||||
"instructions": "You are a helpful assistant.",
|
||||
"modalities": ["text"],
|
||||
"temperature": 0.8
|
||||
}
|
||||
}
|
||||
await ws.send(json.dumps(session_update))
|
||||
|
||||
# Send a message
|
||||
message = {
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{"type": "input_text", "text": "Hello!"}]
|
||||
}
|
||||
}
|
||||
await ws.send(json.dumps(message))
|
||||
|
||||
# Trigger response
|
||||
await ws.send(json.dumps({"type": "response.create"}))
|
||||
|
||||
# Listen for response
|
||||
while True:
|
||||
response = await ws.recv()
|
||||
event = json.loads(response)
|
||||
|
||||
if event['type'] == 'response.text.delta':
|
||||
print(event['delta'], end='', flush=True)
|
||||
elif event['type'] == 'response.done':
|
||||
print("\n✓ Complete")
|
||||
break
|
||||
|
||||
if __name__ == "__main__":
|
||||
asyncio.run(test_text_conversation())
|
||||
```
|
||||
|
||||
## Audio Streaming with Voice Conversation
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
import websockets
|
||||
import json
|
||||
import base64
|
||||
import pyaudio
|
||||
|
||||
LITELLM_API_KEY = "sk-1234"
|
||||
LITELLM_URL = 'ws://localhost:4000/v1/realtime?model=bedrock-sonic'
|
||||
|
||||
# Audio configuration
|
||||
INPUT_RATE = 16000 # Nova Sonic expects 16kHz input
|
||||
OUTPUT_RATE = 24000 # Nova Sonic outputs 24kHz
|
||||
CHUNK = 1024
|
||||
|
||||
async def audio_conversation():
|
||||
# Initialize PyAudio
|
||||
p = pyaudio.PyAudio()
|
||||
|
||||
# Input stream (microphone)
|
||||
input_stream = p.open(
|
||||
format=pyaudio.paInt16,
|
||||
channels=1,
|
||||
rate=INPUT_RATE,
|
||||
input=True,
|
||||
frames_per_buffer=CHUNK
|
||||
)
|
||||
|
||||
# Output stream (speakers)
|
||||
output_stream = p.open(
|
||||
format=pyaudio.paInt16,
|
||||
channels=1,
|
||||
rate=OUTPUT_RATE,
|
||||
output=True,
|
||||
frames_per_buffer=CHUNK
|
||||
)
|
||||
|
||||
async with websockets.connect(
|
||||
LITELLM_URL,
|
||||
additional_headers={"Authorization": f"Bearer {LITELLM_API_KEY}"}
|
||||
) as ws:
|
||||
# Wait for session.created
|
||||
await ws.recv()
|
||||
print("✓ Connected")
|
||||
|
||||
# Configure session with audio
|
||||
session_update = {
|
||||
"type": "session.update",
|
||||
"session": {
|
||||
"instructions": "You are a friendly voice assistant.",
|
||||
"modalities": ["text", "audio"],
|
||||
"voice": "matthew",
|
||||
"input_audio_format": "pcm16",
|
||||
"output_audio_format": "pcm16"
|
||||
}
|
||||
}
|
||||
await ws.send(json.dumps(session_update))
|
||||
print("🎤 Speak into your microphone...")
|
||||
|
||||
async def send_audio():
|
||||
"""Capture and send audio from microphone"""
|
||||
while True:
|
||||
audio_data = input_stream.read(CHUNK, exception_on_overflow=False)
|
||||
audio_b64 = base64.b64encode(audio_data).decode('utf-8')
|
||||
await ws.send(json.dumps({
|
||||
"type": "input_audio_buffer.append",
|
||||
"audio": audio_b64
|
||||
}))
|
||||
await asyncio.sleep(0.01)
|
||||
|
||||
async def receive_audio():
|
||||
"""Receive and play audio responses"""
|
||||
while True:
|
||||
response = await ws.recv()
|
||||
event = json.loads(response)
|
||||
|
||||
if event['type'] == 'response.audio.delta':
|
||||
audio_b64 = event.get('delta', '')
|
||||
if audio_b64:
|
||||
audio_bytes = base64.b64decode(audio_b64)
|
||||
output_stream.write(audio_bytes)
|
||||
|
||||
elif event['type'] == 'response.text.delta':
|
||||
print(event['delta'], end='', flush=True)
|
||||
|
||||
elif event['type'] == 'response.done':
|
||||
print("\n✓ Response complete")
|
||||
|
||||
# Run both tasks concurrently
|
||||
await asyncio.gather(send_audio(), receive_audio())
|
||||
|
||||
if __name__ == "__main__":
|
||||
try:
|
||||
asyncio.run(audio_conversation())
|
||||
except KeyboardInterrupt:
|
||||
print("\n\nGoodbye!")
|
||||
```
|
||||
|
||||
## Using Tools/Function Calling
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
import websockets
|
||||
import json
|
||||
from datetime import datetime
|
||||
|
||||
LITELLM_API_KEY = "sk-1234"
|
||||
LITELLM_URL = 'ws://localhost:4000/v1/realtime?model=bedrock-sonic'
|
||||
|
||||
# Define tools
|
||||
TOOLS = [
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_weather",
|
||||
"description": "Get current weather for a location",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {
|
||||
"type": "string",
|
||||
"description": "City name"
|
||||
}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
|
||||
def get_weather(location: str) -> dict:
|
||||
"""Simulated weather function"""
|
||||
return {
|
||||
"location": location,
|
||||
"temperature": 72,
|
||||
"conditions": "sunny"
|
||||
}
|
||||
|
||||
async def conversation_with_tools():
|
||||
async with websockets.connect(
|
||||
LITELLM_URL,
|
||||
additional_headers={"Authorization": f"Bearer {LITELLM_API_KEY}"}
|
||||
) as ws:
|
||||
# Wait for session.created
|
||||
await ws.recv()
|
||||
|
||||
# Configure session with tools
|
||||
session_update = {
|
||||
"type": "session.update",
|
||||
"session": {
|
||||
"instructions": "You are a helpful assistant with access to tools.",
|
||||
"modalities": ["text"],
|
||||
"tools": TOOLS
|
||||
}
|
||||
}
|
||||
await ws.send(json.dumps(session_update))
|
||||
|
||||
# Send a message that requires a tool
|
||||
message = {
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [{"type": "input_text", "text": "What's the weather in San Francisco?"}]
|
||||
}
|
||||
}
|
||||
await ws.send(json.dumps(message))
|
||||
await ws.send(json.dumps({"type": "response.create"}))
|
||||
|
||||
# Handle responses and tool calls
|
||||
while True:
|
||||
response = await ws.recv()
|
||||
event = json.loads(response)
|
||||
|
||||
if event['type'] == 'response.text.delta':
|
||||
print(event['delta'], end='', flush=True)
|
||||
|
||||
elif event['type'] == 'response.function_call_arguments.done':
|
||||
# Execute the tool
|
||||
function_name = event['name']
|
||||
arguments = json.loads(event['arguments'])
|
||||
|
||||
print(f"\n🔧 Calling {function_name}({arguments})")
|
||||
result = get_weather(**arguments)
|
||||
|
||||
# Send tool result back
|
||||
tool_result = {
|
||||
"type": "conversation.item.create",
|
||||
"item": {
|
||||
"type": "function_call_output",
|
||||
"call_id": event['call_id'],
|
||||
"output": json.dumps(result)
|
||||
}
|
||||
}
|
||||
await ws.send(json.dumps(tool_result))
|
||||
await ws.send(json.dumps({"type": "response.create"}))
|
||||
|
||||
elif event['type'] == 'response.done':
|
||||
print("\n✓ Complete")
|
||||
break
|
||||
|
||||
if __name__ == "__main__":
|
||||
asyncio.run(conversation_with_tools())
|
||||
```
|
||||
|
||||
## Configuration Options
|
||||
|
||||
### Voice Options
|
||||
Available voices: `matthew`, `joanna`, `ruth`, `stephen`, `gregory`, `amy`
|
||||
|
||||
### Audio Formats
|
||||
- **Input**: 16kHz PCM16 (mono)
|
||||
- **Output**: 24kHz PCM16 (mono)
|
||||
|
||||
### Modalities
|
||||
- `["text"]` - Text only
|
||||
- `["audio"]` - Audio only
|
||||
- `["text", "audio"]` - Both text and audio
|
||||
|
||||
## Example Test Scripts
|
||||
|
||||
Complete working examples are available in the LiteLLM repository:
|
||||
|
||||
- **Basic audio streaming**: `test_bedrock_realtime_client.py`
|
||||
- **Simple text test**: `test_bedrock_realtime_simple.py`
|
||||
- **Tool calling**: `test_bedrock_realtime_tools.py`
|
||||
|
||||
## Requirements
|
||||
|
||||
```bash
|
||||
pip install litellm websockets pyaudio
|
||||
```
|
||||
|
||||
## AWS Configuration
|
||||
|
||||
Ensure your AWS credentials are configured:
|
||||
|
||||
```bash
|
||||
export AWS_ACCESS_KEY_ID=your_access_key
|
||||
export AWS_SECRET_ACCESS_KEY=your_secret_key
|
||||
export AWS_REGION_NAME=us-east-1
|
||||
```
|
||||
|
||||
Or use AWS CLI configuration:
|
||||
|
||||
```bash
|
||||
aws configure
|
||||
```
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
### Connection Issues
|
||||
- Ensure LiteLLM proxy is running on the correct port
|
||||
- Verify AWS credentials are properly configured
|
||||
- Check that the Bedrock model is available in your region
|
||||
|
||||
### Audio Issues
|
||||
- Verify PyAudio is properly installed
|
||||
- Check microphone/speaker permissions
|
||||
- Ensure correct sample rates (16kHz input, 24kHz output)
|
||||
|
||||
### Tool Calling Issues
|
||||
- Ensure tools are properly defined in session.update
|
||||
- Verify tool results are sent back with correct call_id
|
||||
- Check that response.create is sent after tool result
|
||||
|
||||
## Related Resources
|
||||
|
||||
- [OpenAI Realtime API Documentation](https://platform.openai.com/docs/guides/realtime)
|
||||
- [Amazon Bedrock Nova Sonic Documentation](https://docs.aws.amazon.com/bedrock/latest/userguide/nova-sonic.html)
|
||||
- [LiteLLM Realtime API Documentation](/docs/realtime)
|
||||
|
|
@ -2,7 +2,7 @@ import Image from '@theme/IdealImage';
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Claude Code Plugin Marketplace
|
||||
# Claude Code Plugin Marketplace (Managed Skills)
|
||||
|
||||
LiteLLM AI Gateway acts as a central registry for Claude Code plugins. Admins can govern which plugins are available across the organization, and engineers can discover and install approved plugins from a single source.
|
||||
|
||||
|
|
@ -252,7 +252,7 @@ curl -X POST http://localhost:4000/claude-code/plugins \
|
|||
}'
|
||||
```
|
||||
|
||||
### 3. Share with Your Team
|
||||
### 3. Use in Claude Code
|
||||
|
||||
Send engineers the marketplace URL:
|
||||
|
||||
|
|
|
|||
BIN
docs/my-website/img/ui_spend_logs_settings.png
Normal file
BIN
docs/my-website/img/ui_spend_logs_settings.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 343 KiB |
384
docs/my-website/release_notes/v1.81.6.md
Normal file
384
docs/my-website/release_notes/v1.81.6.md
Normal file
|
|
@ -0,0 +1,384 @@
|
|||
---
|
||||
title: "v1.81.6 - Logs v2 with Tool Call Tracing"
|
||||
slug: "v1-81-6"
|
||||
date: 2026-01-31T00:00:00
|
||||
authors:
|
||||
- name: Krrish Dholakia
|
||||
title: CEO, LiteLLM
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: CTO, LiteLLM
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
## Deploy this version
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import Image from '@theme/IdealImage';
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="docker" label="Docker">
|
||||
|
||||
```bash
|
||||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
docker.litellm.ai/berriai/litellm:main-v1.81.6
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="pip" label="Pip">
|
||||
|
||||
```bash
|
||||
pip install litellm==1.81.6
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Key Highlights
|
||||
|
||||
Logs View v2 with Tool Call Tracing - Redesigned logs interface with side panel, structured tool visualization, and error message search for faster debugging.
|
||||
|
||||
Let's dive in.
|
||||
|
||||
### Logs View v2 with Tool Call Tracing
|
||||
|
||||
This release introduces comprehensive tool call tracing through LiteLLM's redesigned Logs View v2, enabling developers to debug and monitor AI agent workflows in production environments seamlessly.
|
||||
|
||||
This means you can now onboard use cases like tracing complex multi-step agent interactions, debugging tool execution failures, and monitoring MCP server calls while maintaining full visibility into request/response payloads with syntax highlighting.
|
||||
|
||||
Developers can access the new Logs View through LiteLLM's UI to inspect tool calls in structured format, search logs by error messages or request patterns, and correlate agent activities across sessions with collapsible side panel views.
|
||||
|
||||
{/* TODO: Add image from Slack (group_7219.png) - save as logs_v2_tool_tracing.png */}
|
||||
{/* <Image img={require('../../img/release_notes/logs_v2_tool_tracing.png')} style={{ maxWidth: '800px', width: '100%' }} /> */}
|
||||
|
||||
[Get Started](../../docs/proxy/ui_logs)
|
||||
|
||||
## New Models / Updated Models
|
||||
|
||||
#### New Model Support
|
||||
|
||||
| Provider | Model | Context Window | Input ($/1M tokens) | Output ($/1M tokens) | Features |
|
||||
| -------- | ----- | -------------- | ------------------- | -------------------- | -------- |
|
||||
| AWS Bedrock | `amazon.nova-2-pro-preview-20251202-v1:0` | 1M | $2.19 | $17.50 | Chat completions, vision, video, PDF, function calling, prompt caching, reasoning |
|
||||
| Google Vertex AI | `gemini-robotics-er-1.5-preview` | 1M | $0.30 | $2.50 | Chat completions, multimodal (text, image, video, audio), function calling, reasoning |
|
||||
| OpenRouter | `openrouter/xiaomi/mimo-v2-flash` | 262K | $0.09 | $0.29 | Chat completions, function calling, reasoning |
|
||||
| OpenRouter | `openrouter/moonshotai/kimi-k2.5` | - | - | - | Chat completions |
|
||||
| OpenRouter | `openrouter/z-ai/glm-4.7` | 202K | $0.40 | $1.50 | Chat completions, vision, function calling, reasoning |
|
||||
|
||||
#### Features
|
||||
|
||||
- **[AWS Bedrock](../../docs/providers/bedrock)**
|
||||
- Messages API Bedrock Converse caching and PDF support - [PR #19785](https://github.com/BerriAI/litellm/pull/19785)
|
||||
- Translate advanced-tool-use to Bedrock-specific headers for Claude Opus 4.5 - [PR #19841](https://github.com/BerriAI/litellm/pull/19841)
|
||||
- Support tool search header translation for Sonnet 4.5 - [PR #19871](https://github.com/BerriAI/litellm/pull/19871)
|
||||
- Filter unsupported beta headers for AWS Bedrock Invoke API - [PR #19877](https://github.com/BerriAI/litellm/pull/19877)
|
||||
- Nova grounding improvements - [PR #19598](https://github.com/BerriAI/litellm/pull/19598), [PR #20159](https://github.com/BerriAI/litellm/pull/20159)
|
||||
|
||||
- **[Anthropic](../../docs/providers/anthropic)**
|
||||
- Remove explicit cache_control null in tool_result content - [PR #19919](https://github.com/BerriAI/litellm/pull/19919)
|
||||
- Fix tool handling - [PR #19805](https://github.com/BerriAI/litellm/pull/19805)
|
||||
|
||||
- **[Google Gemini / Vertex AI](../../docs/providers/gemini)**
|
||||
- Add Gemini Robotics-ER 1.5 preview support - [PR #19845](https://github.com/BerriAI/litellm/pull/19845)
|
||||
- Support file retrieval in GoogleAIStudioFilesHandle - [PR #20018](https://github.com/BerriAI/litellm/pull/20018)
|
||||
- Add /delete endpoint support - [PR #20055](https://github.com/BerriAI/litellm/pull/20055)
|
||||
- Add custom_llm_provider as gemini translation - [PR #19988](https://github.com/BerriAI/litellm/pull/19988)
|
||||
- Subtract implicit cached tokens from text_tokens for correct cost calculation - [PR #19775](https://github.com/BerriAI/litellm/pull/19775)
|
||||
- Remove unsupported prompt-caching-scope-2026-01-05 header for vertex ai - [PR #20058](https://github.com/BerriAI/litellm/pull/20058)
|
||||
- Add disable flag for anthropic gemini cache translation - [PR #20052](https://github.com/BerriAI/litellm/pull/20052)
|
||||
- Convert image URLs to base64 in tool messages for Anthropic on Vertex AI - [PR #19896](https://github.com/BerriAI/litellm/pull/19896)
|
||||
|
||||
- **[xAI](../../docs/providers/xai)**
|
||||
- Add grok reasoning content support - [PR #19850](https://github.com/BerriAI/litellm/pull/19850)
|
||||
- Add websearch params support for Responses API - [PR #19915](https://github.com/BerriAI/litellm/pull/19915)
|
||||
- Add routing of xai chat completions to responses when web search options is present - [PR #20051](https://github.com/BerriAI/litellm/pull/20051)
|
||||
- Correct cached token cost calculation - [PR #19772](https://github.com/BerriAI/litellm/pull/19772)
|
||||
|
||||
- **[Azure OpenAI](../../docs/providers/azure)**
|
||||
- Use generic cost calculator for audio token pricing - [PR #19771](https://github.com/BerriAI/litellm/pull/19771)
|
||||
- Allow tool_choice for Azure GPT-5 chat models - [PR #19813](https://github.com/BerriAI/litellm/pull/19813)
|
||||
- Set gpt-5.2-codex mode to responses for Azure and OpenRouter - [PR #19770](https://github.com/BerriAI/litellm/pull/19770)
|
||||
|
||||
- **[OpenAI](../../docs/providers/openai)**
|
||||
- Fix max_input_tokens for gpt-5.2-codex - [PR #20009](https://github.com/BerriAI/litellm/pull/20009)
|
||||
- Fix gpt-image-1.5 cost calculation not including output image tokens - [PR #19515](https://github.com/BerriAI/litellm/pull/19515)
|
||||
|
||||
- **[Hosted VLLM](../../docs/providers/vllm)**
|
||||
- Support thinking parameter in anthropic_messages() and .completion() - [PR #19787](https://github.com/BerriAI/litellm/pull/19787)
|
||||
- Route through base_llm_http_handler to support ssl_verify - [PR #19893](https://github.com/BerriAI/litellm/pull/19893)
|
||||
- Fix vllm embedding format - [PR #20056](https://github.com/BerriAI/litellm/pull/20056)
|
||||
|
||||
- **[OCI GenAI](../../docs/providers/oci)**
|
||||
- Serialize imageUrl as object for OCI GenAI API - [PR #19661](https://github.com/BerriAI/litellm/pull/19661)
|
||||
|
||||
- **[Volcengine](../../docs/providers/volcano)**
|
||||
- Add context for volcengine models (deepseek-v3-2, glm-4-7, kimi-k2-thinking) - [PR #19335](https://github.com/BerriAI/litellm/pull/19335)
|
||||
|
||||
- **[Chinese Providers](../../docs/providers/)**
|
||||
- Add prompt caching and reasoning support for MiniMax, GLM, Xiaomi - [PR #19924](https://github.com/BerriAI/litellm/pull/19924)
|
||||
|
||||
- **[Vercel AI Gateway](../../docs/providers/vercel_ai_gateway)**
|
||||
- Add embeddings support - [PR #19660](https://github.com/BerriAI/litellm/pull/19660)
|
||||
|
||||
### Bug Fixes
|
||||
|
||||
- **[Google](../../docs/providers/gemini)**
|
||||
- Fix gemini-robotics-er-1.5-preview entry - [PR #19974](https://github.com/BerriAI/litellm/pull/19974)
|
||||
|
||||
- **General**
|
||||
- Fix output_tokens_details.reasoning_tokens None - [PR #19914](https://github.com/BerriAI/litellm/pull/19914)
|
||||
- Fix stream_chunk_builder to preserve images from streaming chunks - [PR #19654](https://github.com/BerriAI/litellm/pull/19654)
|
||||
- Fix aspectRatio mapping in image edit - [PR #20053](https://github.com/BerriAI/litellm/pull/20053)
|
||||
- Handle unknown models in Azure AI cost calculator - [PR #20150](https://github.com/BerriAI/litellm/pull/20150)
|
||||
|
||||
- **[GigaChat](../../docs/providers/gigachat)**
|
||||
- Ensure function content is valid JSON - [PR #19232](https://github.com/BerriAI/litellm/pull/19232)
|
||||
|
||||
## LLM API Endpoints
|
||||
|
||||
#### Features
|
||||
|
||||
- **[Messages API (/messages)](../../docs/mcp)**
|
||||
- Add LiteLLM x Claude Agent SDK Integration - [PR #20035](https://github.com/BerriAI/litellm/pull/20035)
|
||||
|
||||
- **[A2A / MCP Gateway API (/a2a, /mcp)](../../docs/mcp)**
|
||||
- Add A2A agent header-based context propagation support - [PR #19504](https://github.com/BerriAI/litellm/pull/19504)
|
||||
- Enable progress notifications for MCP tool calls - [PR #19809](https://github.com/BerriAI/litellm/pull/19809)
|
||||
- Fix support for non-standard MCP URL patterns - [PR #19738](https://github.com/BerriAI/litellm/pull/19738)
|
||||
- Add backward compatibility for legacy A2A card formats (/.well-known/agent.json) - [PR #19949](https://github.com/BerriAI/litellm/pull/19949)
|
||||
- Add support for agent parameter in /interactions endpoint - [PR #19866](https://github.com/BerriAI/litellm/pull/19866)
|
||||
|
||||
- **[Responses API (/responses)](../../docs/response_api)**
|
||||
- Fix custom_llm_provider for provider-specific params - [PR #19798](https://github.com/BerriAI/litellm/pull/19798)
|
||||
- Extract input tokens details as dict in ResponseAPILoggingUtils - [PR #20046](https://github.com/BerriAI/litellm/pull/20046)
|
||||
|
||||
- **[Batch API (/batches)](../../docs/batches)**
|
||||
- Fix /batches to return encoded ids (from managed objects table) - [PR #19040](https://github.com/BerriAI/litellm/pull/19040)
|
||||
- Fix Batch and File user level permissions - [PR #19981](https://github.com/BerriAI/litellm/pull/19981)
|
||||
- Add cost tracking and usage object in retrieve_batch call type - [PR #19986](https://github.com/BerriAI/litellm/pull/19986)
|
||||
|
||||
- **[Embeddings API (/embeddings)](../../docs/embedding/supported_embedding)**
|
||||
- Add supported input formats documentation - [PR #20073](https://github.com/BerriAI/litellm/pull/20073)
|
||||
|
||||
- **[RAG API (/rag/ingest, /vector_store)](../../docs/rag_ingest)**
|
||||
- Add UI for /rag/ingest API - Upload docs, pdfs etc to create vector stores - [PR #19822](https://github.com/BerriAI/litellm/pull/19822)
|
||||
- Add support for using S3 Vectors as Vector Store Provider - [PR #19888](https://github.com/BerriAI/litellm/pull/19888)
|
||||
- Add s3_vectors as provider on /vector_store/search API + UI for creating + PDF support - [PR #19895](https://github.com/BerriAI/litellm/pull/19895)
|
||||
- Add permission management for users and teams on Vector Stores - [PR #19972](https://github.com/BerriAI/litellm/pull/19972)
|
||||
- Enable router support for completions in RAG query pipeline - [PR #19550](https://github.com/BerriAI/litellm/pull/19550)
|
||||
|
||||
- **[Search API (/search)](../../docs/search)**
|
||||
- Add /list endpoint to list what search tools exist in router - [PR #19969](https://github.com/BerriAI/litellm/pull/19969)
|
||||
- Fix router search tools v2 integration - [PR #19840](https://github.com/BerriAI/litellm/pull/19840)
|
||||
|
||||
- **[Passthrough Endpoints (/\{provider\}_passthrough)](../../docs/pass_through/intro)**
|
||||
- Add /openai_passthrough route for OpenAI passthrough requests - [PR #19989](https://github.com/BerriAI/litellm/pull/19989)
|
||||
- Add support for configuring role_mappings via environment variables - [PR #19498](https://github.com/BerriAI/litellm/pull/19498)
|
||||
- Add Vertex AI LLM credentials sensitive keyword "vertex_credentials" for masking - [PR #19551](https://github.com/BerriAI/litellm/pull/19551)
|
||||
- Fix prevention of provider-prefixed model name leaks in responses - [PR #19943](https://github.com/BerriAI/litellm/pull/19943)
|
||||
- Fix proxy support for slashes in Google Vertex generateContent model names - [PR #19737](https://github.com/BerriAI/litellm/pull/19737), [PR #19753](https://github.com/BerriAI/litellm/pull/19753)
|
||||
- Support model names with slashes in Vertex AI passthrough URLs - [PR #19944](https://github.com/BerriAI/litellm/pull/19944)
|
||||
- Fix regression in Vertex AI passthroughs for router models - [PR #19967](https://github.com/BerriAI/litellm/pull/19967)
|
||||
- Add regression tests for Vertex AI passthrough model names - [PR #19855](https://github.com/BerriAI/litellm/pull/19855)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- **General**
|
||||
- Fix token calculations and refactor - [PR #19696](https://github.com/BerriAI/litellm/pull/19696)
|
||||
|
||||
## Management Endpoints / UI
|
||||
|
||||
#### Features
|
||||
|
||||
- **Proxy CLI Auth**
|
||||
- Add configurable CLI JWT expiration via environment variable - [PR #19780](https://github.com/BerriAI/litellm/pull/19780)
|
||||
- Fix team cli auth flow - [PR #19666](https://github.com/BerriAI/litellm/pull/19666)
|
||||
|
||||
- **Virtual Keys**
|
||||
- UI: Auto Truncation of Table Values - [PR #19718](https://github.com/BerriAI/litellm/pull/19718)
|
||||
- Fix Create Key: Expire Key Input Duration - [PR #19807](https://github.com/BerriAI/litellm/pull/19807)
|
||||
- Bulk Update Keys Endpoint - [PR #19886](https://github.com/BerriAI/litellm/pull/19886)
|
||||
|
||||
- **Logs View**
|
||||
- **v2 Logs view with side panel and improved UX** - [PR #20091](https://github.com/BerriAI/litellm/pull/20091)
|
||||
- New View to render "Tools" on Logs View - [PR #20093](https://github.com/BerriAI/litellm/pull/20093)
|
||||
- Add Pretty print view of request/response - [PR #20096](https://github.com/BerriAI/litellm/pull/20096)
|
||||
- Add error_message search in Spend Logs Endpoint - [PR #19960](https://github.com/BerriAI/litellm/pull/19960)
|
||||
- UI: Adding Error message search to ui spend logs - [PR #19963](https://github.com/BerriAI/litellm/pull/19963)
|
||||
- Spend Logs: Settings Modal - [PR #19918](https://github.com/BerriAI/litellm/pull/19918)
|
||||
- Fix error_code in Spend Logs metadata - [PR #20015](https://github.com/BerriAI/litellm/pull/20015)
|
||||
- Spend Logs: Show Current Store and Retention Status - [PR #20017](https://github.com/BerriAI/litellm/pull/20017)
|
||||
- Allow Dynamic Setting of store_prompts_in_spend_logs - [PR #19913](https://github.com/BerriAI/litellm/pull/19913)
|
||||
- [Docs: UI Spend Logs Settings](../../docs/proxy/ui_spend_log_settings) - [PR #20197](https://github.com/BerriAI/litellm/pull/20197)
|
||||
|
||||
- **Models + Endpoints**
|
||||
- Add sortBy and sortOrder params for /v2/model/info - [PR #19903](https://github.com/BerriAI/litellm/pull/19903)
|
||||
- Fix Sorting for /v2/model/info - [PR #19971](https://github.com/BerriAI/litellm/pull/19971)
|
||||
- UI: Model Page Server Sort - [PR #19908](https://github.com/BerriAI/litellm/pull/19908)
|
||||
|
||||
- **Usage & Analytics**
|
||||
- UI: Usage Export: Breakdown by Teams and Keys - [PR #19953](https://github.com/BerriAI/litellm/pull/19953)
|
||||
- UI: Usage: Model Breakdown Per Key - [PR #20039](https://github.com/BerriAI/litellm/pull/20039)
|
||||
|
||||
- **UI Improvements**
|
||||
- UI: Allow Admins to control what pages are visible on LeftNav - [PR #19907](https://github.com/BerriAI/litellm/pull/19907)
|
||||
- UI: Add Light/Dark Mode Switch for Development - [PR #19804](https://github.com/BerriAI/litellm/pull/19804)
|
||||
- UI: Dark Mode: Delete Resource Modal - [PR #20098](https://github.com/BerriAI/litellm/pull/20098)
|
||||
- UI: Tables: Reusable Table Sort Component - [PR #19970](https://github.com/BerriAI/litellm/pull/19970)
|
||||
- UI: New Badge Dot Render - [PR #20024](https://github.com/BerriAI/litellm/pull/20024)
|
||||
- UI: Feedback Prompts: Option To Hide Prompts - [PR #19831](https://github.com/BerriAI/litellm/pull/19831)
|
||||
- UI: Navbar: Fixed Default Logo + Bound Logo Box - [PR #20092](https://github.com/BerriAI/litellm/pull/20092)
|
||||
- UI: Navbar: User Dropdown - [PR #20095](https://github.com/BerriAI/litellm/pull/20095)
|
||||
- Change default key type from 'Default' to 'LLM API' - [PR #19516](https://github.com/BerriAI/litellm/pull/19516)
|
||||
|
||||
- **Team & User Management**
|
||||
- Fix /team/member_add User Email and ID Verifications - [PR #19814](https://github.com/BerriAI/litellm/pull/19814)
|
||||
- Fix SSO Email Case Sensitivity - [PR #19799](https://github.com/BerriAI/litellm/pull/19799)
|
||||
- UI: Internal User: Bulk Add - [PR #19721](https://github.com/BerriAI/litellm/pull/19721)
|
||||
|
||||
- **AI Gateway Features**
|
||||
- Add support for making silent LLM calls without logging - [PR #19544](https://github.com/BerriAI/litellm/pull/19544)
|
||||
- UI: Fix MCP tools instructions to display comma-separated strings - [PR #20101](https://github.com/BerriAI/litellm/pull/20101)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- Fix Model Name During Fallback - [PR #20177](https://github.com/BerriAI/litellm/pull/20177)
|
||||
- Fix Health Endpoints when Callback Objects Defined - [PR #20182](https://github.com/BerriAI/litellm/pull/20182)
|
||||
- Fix Unable to reset user max budget to unlimited - [PR #19796](https://github.com/BerriAI/litellm/pull/19796)
|
||||
- Fix Password comparison with non-ASCII characters - [PR #19568](https://github.com/BerriAI/litellm/pull/19568)
|
||||
- Correct error message for DISABLE_ADMIN_ENDPOINTS - [PR #19861](https://github.com/BerriAI/litellm/pull/19861)
|
||||
- Prevent clearing content filter patterns when editing guardrail - [PR #19671](https://github.com/BerriAI/litellm/pull/19671)
|
||||
- Fix Prompt Studio history to load tools and system messages - [PR #19920](https://github.com/BerriAI/litellm/pull/19920)
|
||||
- Add WATSONX_ZENAPIKEY to WatsonX credentials - [PR #20086](https://github.com/BerriAI/litellm/pull/20086)
|
||||
- UI: Vector Store: Allow Config Defined Models to Be Selected - [PR #20031](https://github.com/BerriAI/litellm/pull/20031)
|
||||
|
||||
## Logging / Guardrail / Prompt Management Integrations
|
||||
|
||||
#### Features
|
||||
|
||||
- **[DataDog](../../docs/proxy/logging#datadog)**
|
||||
- Add agent support for LLM Observability - [PR #19574](https://github.com/BerriAI/litellm/pull/19574)
|
||||
- Add datadog cost management support and fix startup callback issue - [PR #19584](https://github.com/BerriAI/litellm/pull/19584)
|
||||
- Add datadog_llm_observability to /health/services allowed list - [PR #19952](https://github.com/BerriAI/litellm/pull/19952)
|
||||
- Check for agent mode before requiring DD_API_KEY/DD_SITE - [PR #20156](https://github.com/BerriAI/litellm/pull/20156)
|
||||
|
||||
- **[OpenTelemetry](../../docs/observability/opentelemetry_integration)**
|
||||
- Propagate JWT auth metadata to OTEL spans - [PR #19627](https://github.com/BerriAI/litellm/pull/19627)
|
||||
- Fix thread leak in dynamic header path - [PR #19946](https://github.com/BerriAI/litellm/pull/19946)
|
||||
|
||||
- **[Prometheus](../../docs/proxy/logging#prometheus)**
|
||||
- Add callbacks and labels - [PR #19708](https://github.com/BerriAI/litellm/pull/19708)
|
||||
- Add clientip and user agent in metrics - [PR #19717](https://github.com/BerriAI/litellm/pull/19717)
|
||||
- Add tpm-rpm limit metrics - [PR #19725](https://github.com/BerriAI/litellm/pull/19725)
|
||||
- Add model_id label to metrics - [PR #19678](https://github.com/BerriAI/litellm/pull/19678)
|
||||
- Safely handle None metadata in logging - [PR #19691](https://github.com/BerriAI/litellm/pull/19691)
|
||||
- Resolve high CPU when router_settings in DB by avoiding REGISTRY.collect() - [PR #20087](https://github.com/BerriAI/litellm/pull/20087)
|
||||
|
||||
- **[Langfuse](../../docs/proxy/logging#langfuse)**
|
||||
- Add litellm_callback_logging_failures_metric for Langfuse, Langfuse Otel and other Otel providers - [PR #19636](https://github.com/BerriAI/litellm/pull/19636)
|
||||
|
||||
- **General Logging**
|
||||
- Use return value from CustomLogger.async_post_call_success_hook - [PR #19670](https://github.com/BerriAI/litellm/pull/19670)
|
||||
- Add async_post_call_response_headers_hook to CustomLogger - [PR #20083](https://github.com/BerriAI/litellm/pull/20083)
|
||||
- Add mock client factory pattern and mock support for PostHog, Helicone, and Braintrust integrations - [PR #19707](https://github.com/BerriAI/litellm/pull/19707)
|
||||
|
||||
#### Guardrails
|
||||
|
||||
- **[Presidio](../../docs/proxy/guardrails/pii_masking_v2)**
|
||||
- Reuse HTTP connections to prevent performance degradation - [PR #19964](https://github.com/BerriAI/litellm/pull/19964)
|
||||
|
||||
- **Onyx**
|
||||
- Add timeout to onyx guardrail - [PR #19731](https://github.com/BerriAI/litellm/pull/19731)
|
||||
|
||||
- **General**
|
||||
- Add guardrail model argument feature - [PR #19619](https://github.com/BerriAI/litellm/pull/19619)
|
||||
- Fix guardrails issues with streaming-response regex - [PR #19901](https://github.com/BerriAI/litellm/pull/19901)
|
||||
- Remove enterprise requirement for guardrail monitoring (docs) - [PR #19833](https://github.com/BerriAI/litellm/pull/19833)
|
||||
|
||||
## Spend Tracking, Budgets and Rate Limiting
|
||||
|
||||
- Add event-driven coordination for global spend query to prevent cache stampede - [PR #20030](https://github.com/BerriAI/litellm/pull/20030)
|
||||
|
||||
## Performance / Loadbalancing / Reliability improvements
|
||||
|
||||
- **Resolve high CPU when router_settings in DB** - by avoiding REGISTRY.collect() in PrometheusServicesLogger - [PR #20087](https://github.com/BerriAI/litellm/pull/20087)
|
||||
- **Reuse HTTP connections in Presidio** - to prevent performance degradation - [PR #19964](https://github.com/BerriAI/litellm/pull/19964)
|
||||
- **Event-driven coordination for global spend query** - prevent cache stampede - [PR #20030](https://github.com/BerriAI/litellm/pull/20030)
|
||||
- Fix recursive Pydantic validation issue - [PR #19531](https://github.com/BerriAI/litellm/pull/19531)
|
||||
- Refactor argument handling into helper function to reduce code bloat - [PR #19720](https://github.com/BerriAI/litellm/pull/19720)
|
||||
- Optimize logo fetching and resolve MCP import blockers - [PR #19719](https://github.com/BerriAI/litellm/pull/19719)
|
||||
- Improve logo download performance using async HTTP client - [PR #20155](https://github.com/BerriAI/litellm/pull/20155)
|
||||
- Fix server root path configuration - [PR #19790](https://github.com/BerriAI/litellm/pull/19790)
|
||||
- Refactor: Extract transport context creation into separate method - [PR #19794](https://github.com/BerriAI/litellm/pull/19794)
|
||||
- Add native_background_mode configuration to override polling_via_cache for specific models - [PR #19899](https://github.com/BerriAI/litellm/pull/19899)
|
||||
- Initialize tiktoken environment at import time to enable offline usage - [PR #19882](https://github.com/BerriAI/litellm/pull/19882)
|
||||
- Improve tiktoken performance using local cache in lazy loading - [PR #19774](https://github.com/BerriAI/litellm/pull/19774)
|
||||
- Fix timeout errors in chat completion calls to be correctly reported in failure callbacks - [PR #19842](https://github.com/BerriAI/litellm/pull/19842)
|
||||
- Fix environment variable type handling for NUM_RETRIES - [PR #19507](https://github.com/BerriAI/litellm/pull/19507)
|
||||
- Use safe_deep_copy in silent experiment kwargs to prevent mutation - [PR #20170](https://github.com/BerriAI/litellm/pull/20170)
|
||||
- Improve error handling by inspecting BadRequestError after all other policy types - [PR #19878](https://github.com/BerriAI/litellm/pull/19878)
|
||||
|
||||
## Database Changes
|
||||
|
||||
### Schema Updates
|
||||
|
||||
| Table | Change Type | Description | PR | Migration |
|
||||
| ----- | ----------- | ----------- | -- | --------- |
|
||||
| `LiteLLM_ManagedVectorStoresTable` | New Columns | Added `team_id` and `user_id` fields for permission management | [PR #19972](https://github.com/BerriAI/litellm/pull/19972) | [Migration](https://github.com/BerriAI/litellm/blob/main/litellm-proxy-extras/litellm_proxy_extras/migrations/20260131150814_add_team_user_to_vector_stores/migration.sql) |
|
||||
|
||||
### Migration Improvements
|
||||
|
||||
- Fix Docker: Use correct schema path for Prisma generation - [PR #19631](https://github.com/BerriAI/litellm/pull/19631)
|
||||
- Resolve 'relation does not exist' migration errors in setup_database - [PR #19281](https://github.com/BerriAI/litellm/pull/19281)
|
||||
- Fix migration issue and improve Docker image stability - [PR #19843](https://github.com/BerriAI/litellm/pull/19843)
|
||||
- Run Prisma generate as nobody user in non-root Docker container for security - [PR #20000](https://github.com/BerriAI/litellm/pull/20000)
|
||||
- Bump litellm-proxy-extras version to 0.4.28 - [PR #20166](https://github.com/BerriAI/litellm/pull/20166)
|
||||
|
||||
## Documentation Updates
|
||||
|
||||
- **[Add Claude Agents SDK x LiteLLM Guide](../../docs/mcp)** - [PR #20036](https://github.com/BerriAI/litellm/pull/20036)
|
||||
- **[Add Cookbook: Using Claude Agent SDK + MCPs with LiteLLM](https://github.com/BerriAI/litellm/tree/main/cookbook)** - [PR #20081](https://github.com/BerriAI/litellm/pull/20081)
|
||||
- Fix A2A Python SDK URL in documentation - [PR #19832](https://github.com/BerriAI/litellm/pull/19832)
|
||||
- **[Add Sarvam usage documentation](../../docs/providers/sarvam)** - [PR #19844](https://github.com/BerriAI/litellm/pull/19844)
|
||||
- **[Add supported input formats for embeddings](../../docs/embedding/supported_embedding)** - [PR #20073](https://github.com/BerriAI/litellm/pull/20073)
|
||||
- **[UI Spend Logs Settings Docs](../../docs/proxy/ui_spend_log_settings)** - [PR #20197](https://github.com/BerriAI/litellm/pull/20197)
|
||||
- Add OpenAI Agents SDK to OSS Adopters list in README - [PR #19820](https://github.com/BerriAI/litellm/pull/19820)
|
||||
- Update docs: Remove enterprise requirement for guardrail monitoring - [PR #19833](https://github.com/BerriAI/litellm/pull/19833)
|
||||
- Add missing environment variable documentation - [PR #20138](https://github.com/BerriAI/litellm/pull/20138)
|
||||
- Improve documentation blog index page - [PR #20188](https://github.com/BerriAI/litellm/pull/20188)
|
||||
|
||||
## Infrastructure / Testing Improvements
|
||||
|
||||
- Add test coverage for Router.get_valid_args and improve code coverage reporting - [PR #19797](https://github.com/BerriAI/litellm/pull/19797)
|
||||
- Add validation of model cost map as CI job - [PR #19993](https://github.com/BerriAI/litellm/pull/19993)
|
||||
- Add Realtime API benchmarks - [PR #20074](https://github.com/BerriAI/litellm/pull/20074)
|
||||
- Add Init Containers support in community helm chart - [PR #19816](https://github.com/BerriAI/litellm/pull/19816)
|
||||
- Add libsndfile to main Dockerfile for ARM64 audio processing support - [PR #19776](https://github.com/BerriAI/litellm/pull/19776)
|
||||
|
||||
## New Contributors
|
||||
|
||||
* @ruanjf made their first contribution in https://github.com/BerriAI/litellm/pull/19551
|
||||
* @moh-dev-stack made their first contribution in https://github.com/BerriAI/litellm/pull/19507
|
||||
* @formorter made their first contribution in https://github.com/BerriAI/litellm/pull/19498
|
||||
* @priyam-that made their first contribution in https://github.com/BerriAI/litellm/pull/19516
|
||||
* @marcosgriselli made their first contribution in https://github.com/BerriAI/litellm/pull/19550
|
||||
* @natimofeev made their first contribution in https://github.com/BerriAI/litellm/pull/19232
|
||||
* @zifeo made their first contribution in https://github.com/BerriAI/litellm/pull/19805
|
||||
* @pragyasardana made their first contribution in https://github.com/BerriAI/litellm/pull/19816
|
||||
* @ryewilson made their first contribution in https://github.com/BerriAI/litellm/pull/19833
|
||||
* @lizhen921 made their first contribution in https://github.com/BerriAI/litellm/pull/19919
|
||||
* @boarder7395 made their first contribution in https://github.com/BerriAI/litellm/pull/19666
|
||||
* @rushilchugh01 made their first contribution in https://github.com/BerriAI/litellm/pull/19938
|
||||
* @cfchase made their first contribution in https://github.com/BerriAI/litellm/pull/19893
|
||||
* @ayim made their first contribution in https://github.com/BerriAI/litellm/pull/19872
|
||||
* @varunsripad123 made their first contribution in https://github.com/BerriAI/litellm/pull/20018
|
||||
* @nht1206 made their first contribution in https://github.com/BerriAI/litellm/pull/20046
|
||||
* @genga6 made their first contribution in https://github.com/BerriAI/litellm/pull/20009
|
||||
|
||||
**Full Changelog**: https://github.com/BerriAI/litellm/compare/v1.81.3.rc...v1.81.6
|
||||
|
|
@ -314,6 +314,7 @@ const sidebars = {
|
|||
label: "UI Logs",
|
||||
items: [
|
||||
"proxy/ui_logs",
|
||||
"proxy/ui_spend_log_settings",
|
||||
"proxy/ui_logs_sessions",
|
||||
"proxy/deleted_keys_teams"
|
||||
]
|
||||
|
|
@ -441,6 +442,7 @@ const sidebars = {
|
|||
label: "Spend Tracking",
|
||||
items: [
|
||||
"proxy/cost_tracking",
|
||||
"proxy/request_tags",
|
||||
"proxy/custom_pricing",
|
||||
"proxy/pricing_calculator",
|
||||
"proxy/provider_margins",
|
||||
|
|
|
|||
123
docs/my-website/src/theme/BlogListPage/index.js
Normal file
123
docs/my-website/src/theme/BlogListPage/index.js
Normal file
|
|
@ -0,0 +1,123 @@
|
|||
import React from 'react';
|
||||
import Layout from '@theme/Layout';
|
||||
import Link from '@docusaurus/Link';
|
||||
import styles from './styles.module.css';
|
||||
|
||||
const TAG_COLORS = {
|
||||
gemini: {bg: '#d2e3fc', text: '#174ea6', darkBg: '#1a3a5c', darkText: '#8ab4f8'},
|
||||
anthropic: {bg: '#fde0c4', text: '#b33d00', darkBg: '#4a2800', darkText: '#ffb74d'},
|
||||
claude: {bg: '#fde0c4', text: '#b33d00', darkBg: '#4a2800', darkText: '#ffb74d'},
|
||||
llms: {bg: '#c8e6c9', text: '#1b5e20', darkBg: '#1b3d1f', darkText: '#81c784'},
|
||||
};
|
||||
|
||||
function hashHue(str) {
|
||||
let hash = 0;
|
||||
for (let i = 0; i < str.length; i++) {
|
||||
hash = str.charCodeAt(i) + ((hash << 5) - hash);
|
||||
}
|
||||
return Math.abs(hash) % 360;
|
||||
}
|
||||
|
||||
function getTagColor(label) {
|
||||
const key = label.toLowerCase();
|
||||
for (const [k, v] of Object.entries(TAG_COLORS)) {
|
||||
if (key === k) return v;
|
||||
}
|
||||
const hue = hashHue(key);
|
||||
return {
|
||||
bg: `hsl(${hue}, 40%, 90%)`,
|
||||
text: `hsl(${hue}, 60%, 25%)`,
|
||||
darkBg: `hsl(${hue}, 40%, 20%)`,
|
||||
darkText: `hsl(${hue}, 50%, 75%)`,
|
||||
};
|
||||
}
|
||||
|
||||
function formatDate(dateStr) {
|
||||
const d = new Date(dateStr);
|
||||
const now = new Date();
|
||||
const diffDays = Math.floor((now - d) / (1000 * 60 * 60 * 24));
|
||||
if (diffDays <= 0) return 'Today';
|
||||
if (diffDays === 1) return '1d ago';
|
||||
if (diffDays < 30) return `${diffDays}d ago`;
|
||||
return d.toLocaleDateString('en-US', {month: 'short', day: 'numeric', year: 'numeric'});
|
||||
}
|
||||
|
||||
function BlogCard({post, featured}) {
|
||||
const {title, permalink, date, description, tags} = post;
|
||||
const visibleTags = (tags || []).slice(0, 3);
|
||||
|
||||
return (
|
||||
<Link to={permalink} className={styles.cardLink} aria-label={title}>
|
||||
<article className={featured ? styles.cardFeatured : styles.card}>
|
||||
<div className={styles.meta}>
|
||||
<time className={styles.time} dateTime={date}>{formatDate(date)}</time>
|
||||
{featured && <span className={styles.badge}>Latest</span>}
|
||||
</div>
|
||||
<h2 className={styles.title}>{title}</h2>
|
||||
{description && <p className={styles.desc}>{description}</p>}
|
||||
{visibleTags.length > 0 && (
|
||||
<div className={styles.tags}>
|
||||
{visibleTags.map(tag => {
|
||||
const c = getTagColor(tag.label);
|
||||
return (
|
||||
<span key={tag.label} className={styles.tag} style={{
|
||||
'--tag-bg': c.bg, '--tag-text': c.text,
|
||||
'--tag-bg-dark': c.darkBg, '--tag-text-dark': c.darkText,
|
||||
}}>{tag.label}</span>
|
||||
);
|
||||
})}
|
||||
</div>
|
||||
)}
|
||||
<div className={styles.arrow} aria-hidden="true">
|
||||
<svg width="16" height="16" viewBox="0 0 16 16" fill="none">
|
||||
<path d="M6 3l5 5-5 5" stroke="currentColor" strokeWidth="1.5" strokeLinecap="round" strokeLinejoin="round"/>
|
||||
</svg>
|
||||
</div>
|
||||
</article>
|
||||
</Link>
|
||||
);
|
||||
}
|
||||
|
||||
function Pagination({metadata}) {
|
||||
const {previousPage, nextPage} = metadata;
|
||||
if (!previousPage && !nextPage) return null;
|
||||
return (
|
||||
<nav className={styles.pagination} aria-label="Blog list pagination">
|
||||
{previousPage ? (
|
||||
<Link to={previousPage} className={styles.paginationLink}>← Newer posts</Link>
|
||||
) : <span />}
|
||||
{nextPage ? (
|
||||
<Link to={nextPage} className={styles.paginationLink}>Older posts →</Link>
|
||||
) : <span />}
|
||||
</nav>
|
||||
);
|
||||
}
|
||||
|
||||
export default function BlogListPage(props) {
|
||||
const items = props.items || [];
|
||||
const metadata = props.metadata || {};
|
||||
const [first, ...rest] = items;
|
||||
|
||||
return (
|
||||
<Layout
|
||||
title={metadata.blogTitle || 'Blog'}
|
||||
description={metadata.blogDescription || 'Guides, announcements, and best practices from the LiteLLM team.'}
|
||||
>
|
||||
<header className={styles.hero}>
|
||||
<h1 className={styles.heroTitle}>The LiteLLM Blog</h1>
|
||||
<p className={styles.heroSubtitle}>Guides, announcements, and best practices from the LiteLLM team.</p>
|
||||
</header>
|
||||
|
||||
<main className={styles.grid}>
|
||||
{first && (
|
||||
<BlogCard post={first.content.metadata} featured />
|
||||
)}
|
||||
{rest.map(({content}) => (
|
||||
<BlogCard key={content.metadata.permalink} post={content.metadata} />
|
||||
))}
|
||||
</main>
|
||||
|
||||
<Pagination metadata={metadata} />
|
||||
</Layout>
|
||||
);
|
||||
}
|
||||
163
docs/my-website/src/theme/BlogListPage/styles.module.css
Normal file
163
docs/my-website/src/theme/BlogListPage/styles.module.css
Normal file
|
|
@ -0,0 +1,163 @@
|
|||
.hero {
|
||||
max-width: 960px;
|
||||
margin: 0 auto;
|
||||
padding: 3rem 1.5rem 1rem;
|
||||
text-align: center;
|
||||
}
|
||||
|
||||
.heroTitle {
|
||||
font-size: 2.25rem;
|
||||
font-weight: 700;
|
||||
margin-bottom: 0.25rem;
|
||||
letter-spacing: -0.02em;
|
||||
}
|
||||
|
||||
.heroSubtitle {
|
||||
color: var(--ifm-color-emphasis-600);
|
||||
font-size: 1.1rem;
|
||||
margin-bottom: 0;
|
||||
}
|
||||
|
||||
.grid {
|
||||
max-width: 960px;
|
||||
margin: 0 auto;
|
||||
padding: 1.5rem;
|
||||
display: grid;
|
||||
gap: 1rem;
|
||||
}
|
||||
|
||||
.cardLink {
|
||||
display: block;
|
||||
text-decoration: none;
|
||||
color: inherit;
|
||||
}
|
||||
|
||||
.card {
|
||||
position: relative;
|
||||
border: 1px solid var(--ifm-color-emphasis-200);
|
||||
border-radius: 12px;
|
||||
padding: 1.5rem;
|
||||
padding-right: 2.5rem;
|
||||
height: 100%;
|
||||
transition: border-color 0.15s, transform 0.15s, background 0.15s;
|
||||
background: var(--ifm-background-surface-color, var(--ifm-background-color));
|
||||
}
|
||||
|
||||
.card:hover {
|
||||
border-color: var(--ifm-color-primary);
|
||||
transform: translateY(-2px);
|
||||
background: var(--ifm-color-emphasis-100);
|
||||
}
|
||||
|
||||
.cardFeatured {
|
||||
composes: card;
|
||||
border-color: var(--ifm-color-primary-lighter);
|
||||
background: var(--ifm-color-emphasis-100);
|
||||
}
|
||||
|
||||
.meta {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
gap: 0.5rem;
|
||||
margin-bottom: 0.5rem;
|
||||
}
|
||||
|
||||
.time {
|
||||
font-size: 0.8rem;
|
||||
font-weight: 500;
|
||||
color: var(--ifm-color-emphasis-600);
|
||||
text-transform: uppercase;
|
||||
letter-spacing: 0.04em;
|
||||
}
|
||||
|
||||
.badge {
|
||||
font-size: 0.65rem;
|
||||
font-weight: 600;
|
||||
text-transform: uppercase;
|
||||
letter-spacing: 0.06em;
|
||||
padding: 2px 8px;
|
||||
border-radius: 99px;
|
||||
background: var(--ifm-color-primary);
|
||||
color: #fff;
|
||||
}
|
||||
|
||||
.title {
|
||||
font-size: 1.15rem;
|
||||
font-weight: 600;
|
||||
margin: 0 0 0.4rem;
|
||||
line-height: 1.35;
|
||||
}
|
||||
|
||||
.desc {
|
||||
font-size: 0.88rem;
|
||||
color: var(--ifm-color-emphasis-700);
|
||||
line-height: 1.5;
|
||||
margin: 0 0 0.75rem;
|
||||
}
|
||||
|
||||
.tags {
|
||||
display: flex;
|
||||
gap: 6px;
|
||||
flex-wrap: wrap;
|
||||
}
|
||||
|
||||
.tag {
|
||||
font-size: 0.7rem;
|
||||
font-weight: 500;
|
||||
padding: 2px 10px;
|
||||
border-radius: 99px;
|
||||
background: var(--tag-bg);
|
||||
color: var(--tag-text);
|
||||
}
|
||||
|
||||
:global([data-theme='dark']) .tag {
|
||||
background: var(--tag-bg-dark);
|
||||
color: var(--tag-text-dark);
|
||||
}
|
||||
|
||||
.arrow {
|
||||
position: absolute;
|
||||
right: 1rem;
|
||||
top: 50%;
|
||||
transform: translateY(-50%);
|
||||
color: var(--ifm-color-emphasis-400);
|
||||
transition: color 0.15s, transform 0.15s;
|
||||
}
|
||||
|
||||
.card:hover .arrow {
|
||||
color: var(--ifm-color-primary);
|
||||
transform: translateY(-50%) translateX(3px);
|
||||
}
|
||||
|
||||
.pagination {
|
||||
max-width: 960px;
|
||||
margin: 0 auto;
|
||||
padding: 1rem 1.5rem 3rem;
|
||||
display: flex;
|
||||
justify-content: space-between;
|
||||
}
|
||||
|
||||
.paginationLink {
|
||||
font-size: 0.9rem;
|
||||
font-weight: 500;
|
||||
color: var(--ifm-color-primary);
|
||||
text-decoration: none;
|
||||
}
|
||||
|
||||
.paginationLink:hover {
|
||||
text-decoration: underline;
|
||||
}
|
||||
|
||||
@media (min-width: 640px) {
|
||||
.grid {
|
||||
grid-template-columns: repeat(2, 1fr);
|
||||
}
|
||||
|
||||
.grid .cardLink:first-child {
|
||||
grid-column: 1 / -1;
|
||||
}
|
||||
|
||||
.grid .cardLink:last-child:nth-child(even) {
|
||||
grid-column: 1 / -1;
|
||||
}
|
||||
}
|
||||
|
|
@ -282,6 +282,8 @@ async def get_vector_store_info(
|
|||
updated_at=vector_store.get("updated_at") or None,
|
||||
litellm_credential_name=vector_store.get("litellm_credential_name"),
|
||||
litellm_params=vector_store.get("litellm_params") or None,
|
||||
team_id=vector_store.get("team_id"),
|
||||
user_id=vector_store.get("user_id"),
|
||||
)
|
||||
return {"vector_store": vector_store_pydantic_obj}
|
||||
|
||||
|
|
|
|||
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.28-py3-none-any.whl
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.28-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.28.tar.gz
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.28.tar.gz
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.29-py3-none-any.whl
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.29-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.29.tar.gz
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.29.tar.gz
vendored
Normal file
Binary file not shown.
|
|
@ -0,0 +1,8 @@
|
|||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_VerificationToken_user_id_team_id_idx" ON "LiteLLM_VerificationToken"("user_id", "team_id");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_VerificationToken_team_id_idx" ON "LiteLLM_VerificationToken"("team_id");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_VerificationToken_budget_reset_at_expires_idx" ON "LiteLLM_VerificationToken"("budget_reset_at", "expires");
|
||||
|
|
@ -0,0 +1,10 @@
|
|||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_ManagedVectorStoresTable" ADD COLUMN "team_id" TEXT,
|
||||
ADD COLUMN "user_id" TEXT;
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_ManagedVectorStoresTable_team_id_idx" ON "LiteLLM_ManagedVectorStoresTable"("team_id");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_ManagedVectorStoresTable_user_id_idx" ON "LiteLLM_ManagedVectorStoresTable"("user_id");
|
||||
|
||||
|
|
@ -5,6 +5,7 @@ datasource client {
|
|||
|
||||
generator client {
|
||||
provider = "prisma-client-py"
|
||||
binaryTargets = ["native", "debian-openssl-1.1.x", "debian-openssl-3.0.x", "linux-musl", "linux-musl-openssl-3.0.x"]
|
||||
}
|
||||
|
||||
// Budget / Rate Limits for an org
|
||||
|
|
@ -304,6 +305,16 @@ model LiteLLM_VerificationToken {
|
|||
litellm_budget_table LiteLLM_BudgetTable? @relation(fields: [budget_id], references: [budget_id])
|
||||
litellm_organization_table LiteLLM_OrganizationTable? @relation(fields: [organization_id], references: [organization_id])
|
||||
object_permission LiteLLM_ObjectPermissionTable? @relation(fields: [object_permission_id], references: [object_permission_id])
|
||||
|
||||
// SELECT COUNT(*) FROM (SELECT "public"."LiteLLM_VerificationToken"."token" FROM "public"."LiteLLM_VerificationToken" WHERE ("public"."LiteLLM_VerificationToken"."user_id" = $1 AND ("public"."LiteLLM_VerificationToken"."team_id" IS NULL OR "public"."LiteLLM_VerificationToken"."team_id" <> $2)) OFFSET $3 ) AS "sub"
|
||||
// SELECT ... FROM "public"."LiteLLM_VerificationToken" WHERE "public"."LiteLLM_VerificationToken"."user_id" = $1 OFFSET $2
|
||||
@@index([user_id, team_id])
|
||||
|
||||
// SELECT ... FROM "public"."LiteLLM_VerificationToken" WHERE "public"."LiteLLM_VerificationToken"."team_id" = $1 OFFSET $2
|
||||
@@index([team_id])
|
||||
|
||||
// SELECT ... FROM "public"."LiteLLM_VerificationToken" WHERE (("public"."LiteLLM_VerificationToken"."expires" IS NULL OR "public"."LiteLLM_VerificationToken"."expires" > $1) AND "public"."LiteLLM_VerificationToken"."budget_reset_at" < $2) OFFSET $3
|
||||
@@index([budget_reset_at, expires])
|
||||
}
|
||||
|
||||
// Audit table for deleted keys - preserves spend and key information for historical tracking
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "litellm-proxy-extras"
|
||||
version = "0.4.27"
|
||||
version = "0.4.29"
|
||||
description = "Additional files for the LiteLLM Proxy. Reduces the size of the main litellm package."
|
||||
authors = ["BerriAI"]
|
||||
readme = "README.md"
|
||||
|
|
@ -22,7 +22,7 @@ requires = ["poetry-core"]
|
|||
build-backend = "poetry.core.masonry.api"
|
||||
|
||||
[tool.commitizen]
|
||||
version = "0.4.27"
|
||||
version = "0.4.29"
|
||||
version_files = [
|
||||
"pyproject.toml:version",
|
||||
"../requirements.txt:litellm-proxy-extras==",
|
||||
|
|
|
|||
|
|
@ -351,7 +351,7 @@ default_team_settings: Optional[List] = None
|
|||
max_user_budget: Optional[float] = None
|
||||
default_max_internal_user_budget: Optional[float] = None
|
||||
max_internal_user_budget: Optional[float] = None
|
||||
max_ui_session_budget: Optional[float] = 10 # $10 USD budgets for UI Chat sessions
|
||||
max_ui_session_budget: Optional[float] = 0.25 # $0.25 USD budgets for UI Chat sessions
|
||||
internal_user_budget_duration: Optional[str] = None
|
||||
tag_budget_config: Optional[Dict[str, "BudgetConfig"]] = None
|
||||
max_end_user_budget: Optional[float] = None
|
||||
|
|
|
|||
|
|
@ -876,7 +876,9 @@ async def acancel_batch(
|
|||
try:
|
||||
loop = asyncio.get_event_loop()
|
||||
kwargs["acancel_batch"] = True
|
||||
model = kwargs.pop("model", None)
|
||||
# Preserve model parameter - only pop from kwargs if it exists there
|
||||
# (to avoid passing it twice), otherwise keep the function parameter value
|
||||
model = kwargs.pop("model", None) or model
|
||||
|
||||
# Use a partial function to pass your keyword arguments
|
||||
func = partial(
|
||||
|
|
|
|||
|
|
@ -17,7 +17,7 @@ from typing import (
|
|||
Optional,
|
||||
Tuple,
|
||||
Union,
|
||||
cast
|
||||
cast,
|
||||
)
|
||||
|
||||
from openai.types.responses.tool_param import FunctionToolParam
|
||||
|
|
@ -744,11 +744,18 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
if "tools" not in responses_api_request or responses_api_request["tools"] is None:
|
||||
responses_api_request["tools"] = []
|
||||
|
||||
# Get the tools list with proper type narrowing
|
||||
tools = responses_api_request["tools"]
|
||||
if tools is None:
|
||||
tools = []
|
||||
responses_api_request["tools"] = tools
|
||||
|
||||
web_search_tool: Dict[str, Any] = {"type": "web_search"}
|
||||
if isinstance(web_search_options, dict):
|
||||
web_search_tool.update(web_search_options)
|
||||
|
||||
responses_api_request["tools"].append(web_search_tool)
|
||||
# Cast to Any to match the expected union type for tools list items
|
||||
tools.append(cast(Any, web_search_tool))
|
||||
|
||||
def _transform_response_format_to_text_format(
|
||||
self, response_format: Union[Dict[str, Any], Any]
|
||||
|
|
|
|||
|
|
@ -11,10 +11,12 @@ from mcp import ClientSession, ReadResourceResult, Resource, StdioServerParamete
|
|||
from mcp.client.sse import sse_client
|
||||
from mcp.client.stdio import stdio_client
|
||||
|
||||
streamable_http_client: Optional[Any] = None
|
||||
try:
|
||||
from mcp.client.streamable_http import streamable_http_client # type: ignore
|
||||
import mcp.client.streamable_http as streamable_http_module # type: ignore
|
||||
streamable_http_client = getattr(streamable_http_module, "streamable_http_client", None)
|
||||
except ImportError:
|
||||
streamable_http_client = None
|
||||
pass
|
||||
from mcp.types import CallToolRequestParams as MCPCallToolRequestParams
|
||||
from mcp.types import CallToolResult as MCPCallToolResult
|
||||
from mcp.types import (
|
||||
|
|
@ -111,6 +113,12 @@ class MCPClient:
|
|||
), None
|
||||
|
||||
# HTTP transport (default)
|
||||
if streamable_http_client is None:
|
||||
raise ImportError(
|
||||
"streamable_http_client is not available. "
|
||||
"Please install mcp with HTTP support."
|
||||
)
|
||||
|
||||
headers = self._get_auth_headers()
|
||||
httpx_client_factory = self._create_httpx_client_factory()
|
||||
verbose_logger.debug(
|
||||
|
|
|
|||
|
|
@ -9,7 +9,7 @@ import asyncio
|
|||
import contextvars
|
||||
import os
|
||||
import time
|
||||
import uuid
|
||||
import uuid as uuid_module
|
||||
from functools import partial
|
||||
from typing import Any, Coroutine, Dict, Literal, Optional, Union, cast
|
||||
|
||||
|
|
@ -451,7 +451,7 @@ def file_retrieve(
|
|||
stream=False,
|
||||
call_type="afile_retrieve" if _is_async else "file_retrieve",
|
||||
start_time=time.time(),
|
||||
litellm_call_id=kwargs.get("litellm_call_id", str(uuid.uuid4())),
|
||||
litellm_call_id=kwargs.get("litellm_call_id", str(uuid_module.uuid4())),
|
||||
function_id=str(kwargs.get("id") or ""),
|
||||
)
|
||||
|
||||
|
|
@ -660,7 +660,7 @@ def file_delete(
|
|||
stream=False,
|
||||
call_type="afile_delete" if _is_async else "file_delete",
|
||||
start_time=time.time(),
|
||||
litellm_call_id=kwargs.get("litellm_call_id", str(uuid.uuid4())),
|
||||
litellm_call_id=kwargs.get("litellm_call_id", str(uuid_module.uuid4())),
|
||||
function_id=str(kwargs.get("id") or ""),
|
||||
)
|
||||
|
||||
|
|
@ -793,7 +793,7 @@ def file_list(
|
|||
stream=False,
|
||||
call_type="afile_list" if _is_async else "file_list",
|
||||
start_time=time.time(),
|
||||
litellm_call_id=kwargs.get("litellm_call_id", str(uuid.uuid4())),
|
||||
litellm_call_id=kwargs.get("litellm_call_id", str(uuid_module.uuid4())),
|
||||
function_id=str(kwargs.get("id", "")),
|
||||
)
|
||||
|
||||
|
|
|
|||
|
|
@ -1378,6 +1378,11 @@ Model Info:
|
|||
"""
|
||||
if self.alerting is None:
|
||||
return
|
||||
|
||||
# Start periodic flush if not already started
|
||||
if not self.periodic_started and self.alerting is not None and len(self.alerting) > 0:
|
||||
asyncio.create_task(self.periodic_flush())
|
||||
self.periodic_started = True
|
||||
|
||||
if (
|
||||
"webhook" in self.alerting
|
||||
|
|
|
|||
|
|
@ -55,14 +55,9 @@ class DataDogLLMObsLogger(CustomBatchLogger):
|
|||
create_mock_datadog_client()
|
||||
verbose_logger.debug("[DATADOG MOCK] DataDogLLMObs logger initialized in mock mode")
|
||||
|
||||
if os.getenv("DD_API_KEY", None) is None:
|
||||
raise Exception("DD_API_KEY is not set, set 'DD_API_KEY=<>'")
|
||||
if os.getenv("DD_SITE", None) is None:
|
||||
raise Exception(
|
||||
"DD_SITE is not set, set 'DD_SITE=<>', example sit = `us5.datadoghq.com`"
|
||||
)
|
||||
# Configure DataDog endpoint (Agent or Direct API)
|
||||
# Use LITELLM_DD_AGENT_HOST to avoid conflicts with ddtrace's DD_AGENT_HOST
|
||||
# Check for agent mode FIRST - agent mode doesn't require DD_API_KEY or DD_SITE
|
||||
dd_agent_host = os.getenv("LITELLM_DD_AGENT_HOST")
|
||||
|
||||
self.async_client = get_async_httpx_client(
|
||||
|
|
@ -73,6 +68,13 @@ class DataDogLLMObsLogger(CustomBatchLogger):
|
|||
if dd_agent_host:
|
||||
self._configure_dd_agent(dd_agent_host=dd_agent_host)
|
||||
else:
|
||||
# Only require DD_API_KEY and DD_SITE for direct API mode
|
||||
if os.getenv("DD_API_KEY", None) is None:
|
||||
raise Exception("DD_API_KEY is not set, set 'DD_API_KEY=<>'")
|
||||
if os.getenv("DD_SITE", None) is None:
|
||||
raise Exception(
|
||||
"DD_SITE is not set, set 'DD_SITE=<>', example sit = `us5.datadoghq.com`"
|
||||
)
|
||||
self._configure_dd_direct_api()
|
||||
|
||||
# Optional override for testing
|
||||
|
|
|
|||
|
|
@ -1631,7 +1631,7 @@ class OpenTelemetry(CustomLogger):
|
|||
)
|
||||
|
||||
except Exception as e:
|
||||
self.handle_callback_failure(callback_name= self.callback_name)
|
||||
self.handle_callback_failure(callback_name=self.callback_name or "opentelemetry")
|
||||
verbose_logger.exception(
|
||||
"OpenTelemetry logging error in set_attributes %s", str(e)
|
||||
)
|
||||
|
|
|
|||
|
|
@ -2435,6 +2435,36 @@ class Logging(LiteLLMLoggingBaseClass):
|
|||
standard_built_in_tools_params=self.standard_built_in_tools_params,
|
||||
)
|
||||
|
||||
# print standard logging payload
|
||||
if (
|
||||
standard_logging_payload := self.model_call_details.get(
|
||||
"standard_logging_object"
|
||||
)
|
||||
) is not None:
|
||||
emit_standard_logging_payload(standard_logging_payload)
|
||||
elif self.call_type == "pass_through_endpoint":
|
||||
print_verbose(
|
||||
"Async success callbacks: Got a pass-through endpoint response"
|
||||
)
|
||||
|
||||
self.model_call_details["async_complete_streaming_response"] = result
|
||||
|
||||
# cost calculation not possible for pass-through
|
||||
self.model_call_details["response_cost"] = None
|
||||
|
||||
## STANDARDIZED LOGGING PAYLOAD
|
||||
self.model_call_details[
|
||||
"standard_logging_object"
|
||||
] = get_standard_logging_object_payload(
|
||||
kwargs=self.model_call_details,
|
||||
init_response_obj=result,
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
logging_obj=self,
|
||||
status="success",
|
||||
standard_built_in_tools_params=self.standard_built_in_tools_params,
|
||||
)
|
||||
|
||||
# print standard logging payload
|
||||
if (
|
||||
standard_logging_payload := self.model_call_details.get(
|
||||
|
|
|
|||
|
|
@ -215,6 +215,9 @@ def _get_token_base_cost(
|
|||
cache_creation_tiered_key = (
|
||||
f"cache_creation_input_token_cost_above_{threshold_str}_tokens"
|
||||
)
|
||||
cache_creation_1hr_tiered_key = (
|
||||
f"cache_creation_input_token_cost_above_1hr_above_{threshold_str}_tokens"
|
||||
)
|
||||
cache_read_tiered_key = (
|
||||
f"cache_read_input_token_cost_above_{threshold_str}_tokens"
|
||||
)
|
||||
|
|
@ -229,6 +232,16 @@ def _get_token_base_cost(
|
|||
),
|
||||
)
|
||||
|
||||
if cache_creation_1hr_tiered_key in model_info:
|
||||
cache_creation_cost_above_1hr = cast(
|
||||
float,
|
||||
_get_cost_per_unit(
|
||||
model_info,
|
||||
cache_creation_1hr_tiered_key,
|
||||
cache_creation_cost_above_1hr,
|
||||
),
|
||||
)
|
||||
|
||||
if cache_read_tiered_key in model_info:
|
||||
cache_read_cost = cast(
|
||||
float,
|
||||
|
|
|
|||
|
|
@ -17,15 +17,16 @@ from litellm.types.rerank import RerankRequest
|
|||
|
||||
|
||||
class ModelParamHelper:
|
||||
# Cached at class level — deterministic set built from static OpenAI type annotations
|
||||
_relevant_logging_args: frozenset = frozenset()
|
||||
|
||||
@staticmethod
|
||||
def get_standard_logging_model_parameters(
|
||||
model_parameters: dict,
|
||||
) -> dict:
|
||||
""" """
|
||||
standard_logging_model_parameters: dict = {}
|
||||
supported_model_parameters = (
|
||||
ModelParamHelper._get_relevant_args_to_use_for_logging()
|
||||
)
|
||||
supported_model_parameters = ModelParamHelper._relevant_logging_args
|
||||
|
||||
for key, value in model_parameters.items():
|
||||
if key in supported_model_parameters:
|
||||
|
|
@ -172,3 +173,8 @@ class ModelParamHelper:
|
|||
Get the kwargs to exclude from the cache key
|
||||
"""
|
||||
return set(["metadata"])
|
||||
|
||||
|
||||
ModelParamHelper._relevant_logging_args = frozenset(
|
||||
ModelParamHelper._get_relevant_args_to_use_for_logging()
|
||||
)
|
||||
|
|
|
|||
|
|
@ -3399,6 +3399,59 @@ def _convert_to_bedrock_tool_call_result(
|
|||
return content_block
|
||||
|
||||
|
||||
def _deduplicate_bedrock_content_blocks(
|
||||
blocks: List[BedrockContentBlock],
|
||||
block_key: str,
|
||||
id_key: str = "toolUseId",
|
||||
) -> List[BedrockContentBlock]:
|
||||
"""
|
||||
Remove duplicate content blocks that share the same ID under ``block_key``.
|
||||
|
||||
Bedrock requires all toolResult and toolUse IDs within a single message to
|
||||
be unique. When merging consecutive messages, duplicates can occur if the
|
||||
same tool_call_id appears multiple times in conversation history.
|
||||
|
||||
When duplicates exist, the first occurrence is retained and subsequent ones
|
||||
are discarded. A warning is logged for every dropped block so that
|
||||
upstream duplication bugs remain visible.
|
||||
|
||||
Blocks that do not contain ``block_key`` (e.g., cachePoint, text) are
|
||||
always preserved.
|
||||
|
||||
Args:
|
||||
blocks: The list of Bedrock content blocks to deduplicate.
|
||||
block_key: The dict key to inspect (e.g. ``"toolResult"`` or ``"toolUse"``).
|
||||
id_key: The nested key that holds the unique ID (default ``"toolUseId"``).
|
||||
"""
|
||||
seen_ids: Set[str] = set()
|
||||
deduplicated: List[BedrockContentBlock] = []
|
||||
for block in blocks:
|
||||
keyed = block.get(block_key)
|
||||
if keyed is not None and isinstance(keyed, dict):
|
||||
block_id = keyed.get(id_key)
|
||||
if block_id:
|
||||
if block_id in seen_ids:
|
||||
verbose_logger.warning(
|
||||
"Bedrock Converse: dropping duplicate %s block with "
|
||||
"%s=%s. This may indicate duplicate tool messages in "
|
||||
"conversation history.",
|
||||
block_key,
|
||||
id_key,
|
||||
block_id,
|
||||
)
|
||||
continue
|
||||
seen_ids.add(block_id)
|
||||
deduplicated.append(block)
|
||||
return deduplicated
|
||||
|
||||
|
||||
def _deduplicate_bedrock_tool_content(
|
||||
tool_content: List[BedrockContentBlock],
|
||||
) -> List[BedrockContentBlock]:
|
||||
"""Convenience wrapper: deduplicate ``toolResult`` blocks by ``toolUseId``."""
|
||||
return _deduplicate_bedrock_content_blocks(tool_content, "toolResult")
|
||||
|
||||
|
||||
def _insert_assistant_continue_message(
|
||||
messages: List[BedrockMessageBlock],
|
||||
assistant_continue_message: Optional[
|
||||
|
|
@ -3867,6 +3920,8 @@ class BedrockConverseMessagesProcessor:
|
|||
tool_content.append(cache_point_block)
|
||||
|
||||
msg_i += 1
|
||||
# Deduplicate toolResult blocks with the same toolUseId
|
||||
tool_content = _deduplicate_bedrock_tool_content(tool_content)
|
||||
if tool_content:
|
||||
# if last message was a 'user' message, then add a blank assistant message (bedrock requires alternating roles)
|
||||
if len(contents) > 0 and contents[-1]["role"] == "user":
|
||||
|
|
@ -3980,6 +4035,8 @@ class BedrockConverseMessagesProcessor:
|
|||
|
||||
msg_i += 1
|
||||
|
||||
assistant_content = _deduplicate_bedrock_content_blocks(assistant_content, "toolUse")
|
||||
|
||||
if assistant_content:
|
||||
contents.append(
|
||||
BedrockMessageBlock(role="assistant", content=assistant_content)
|
||||
|
|
@ -4230,6 +4287,8 @@ def _bedrock_converse_messages_pt( # noqa: PLR0915
|
|||
tool_content.append(cache_point_block)
|
||||
|
||||
msg_i += 1
|
||||
# Deduplicate toolResult blocks with the same toolUseId
|
||||
tool_content = _deduplicate_bedrock_tool_content(tool_content)
|
||||
if tool_content:
|
||||
# if last message was a 'user' message, then add a blank assistant message (bedrock requires alternating roles)
|
||||
if len(contents) > 0 and contents[-1]["role"] == "user":
|
||||
|
|
@ -4336,6 +4395,8 @@ def _bedrock_converse_messages_pt( # noqa: PLR0915
|
|||
|
||||
msg_i += 1
|
||||
|
||||
assistant_content = _deduplicate_bedrock_content_blocks(assistant_content, "toolUse")
|
||||
|
||||
if assistant_content:
|
||||
contents.append(
|
||||
BedrockMessageBlock(role="assistant", content=assistant_content)
|
||||
|
|
@ -4395,6 +4456,32 @@ def add_cache_point_tool_block(tool: dict) -> Optional[BedrockToolBlock]:
|
|||
return None
|
||||
|
||||
|
||||
def _is_bedrock_tool_block(tool: dict) -> bool:
|
||||
"""
|
||||
Check if a tool is already a BedrockToolBlock.
|
||||
|
||||
BedrockToolBlock has one of: systemTool, toolSpec, or cachePoint.
|
||||
This is used to detect tools that are already in Bedrock format
|
||||
(e.g., systemTool for Nova grounding) vs OpenAI-style function tools
|
||||
that need transformation.
|
||||
|
||||
Args:
|
||||
tool: The tool dict to check
|
||||
|
||||
Returns:
|
||||
True if the tool is already a BedrockToolBlock, False otherwise
|
||||
|
||||
Examples:
|
||||
>>> _is_bedrock_tool_block({"systemTool": {"name": "nova_grounding"}})
|
||||
True
|
||||
>>> _is_bedrock_tool_block({"type": "function", "function": {...}})
|
||||
False
|
||||
"""
|
||||
return isinstance(tool, dict) and (
|
||||
"systemTool" in tool or "toolSpec" in tool or "cachePoint" in tool
|
||||
)
|
||||
|
||||
|
||||
def _bedrock_tools_pt(tools: List) -> List[BedrockToolBlock]:
|
||||
"""
|
||||
OpenAI tools looks like:
|
||||
|
|
@ -4448,7 +4535,13 @@ def _bedrock_tools_pt(tools: List) -> List[BedrockToolBlock]:
|
|||
|
||||
tool_block_list: List[BedrockToolBlock] = []
|
||||
for tool in tools:
|
||||
# Handle regular function tools
|
||||
# Check if tool is already a BedrockToolBlock (e.g., systemTool for Nova grounding)
|
||||
if _is_bedrock_tool_block(tool):
|
||||
# Already a BedrockToolBlock, pass it through
|
||||
tool_block_list.append(tool) # type: ignore
|
||||
continue
|
||||
|
||||
# Handle regular OpenAI-style function tools
|
||||
parameters = tool.get("function", {}).get(
|
||||
"parameters", {"type": "object", "properties": {}}
|
||||
)
|
||||
|
|
|
|||
|
|
@ -74,7 +74,7 @@ class AnthropicMessagesHandler(BaseTranslation):
|
|||
if messages is None:
|
||||
return data
|
||||
|
||||
chat_completion_compatible_request = (
|
||||
chat_completion_compatible_request, tool_name_mapping = (
|
||||
LiteLLMAnthropicMessagesAdapter().translate_anthropic_to_openai(
|
||||
anthropic_message_request=cast(AnthropicMessagesRequest, data)
|
||||
)
|
||||
|
|
|
|||
|
|
@ -6,6 +6,7 @@ from typing import (
|
|||
Dict,
|
||||
List,
|
||||
Optional,
|
||||
Tuple,
|
||||
Union,
|
||||
cast,
|
||||
)
|
||||
|
|
@ -47,8 +48,14 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
top_p: Optional[float] = None,
|
||||
output_format: Optional[Dict] = None,
|
||||
extra_kwargs: Optional[Dict[str, Any]] = None,
|
||||
) -> Dict[str, Any]:
|
||||
"""Prepare kwargs for litellm.completion/acompletion"""
|
||||
) -> Tuple[Dict[str, Any], Dict[str, str]]:
|
||||
"""Prepare kwargs for litellm.completion/acompletion.
|
||||
|
||||
Returns:
|
||||
Tuple of (completion_kwargs, tool_name_mapping)
|
||||
- tool_name_mapping maps truncated tool names back to original names
|
||||
for tools that exceeded OpenAI's 64-char limit
|
||||
"""
|
||||
from litellm.litellm_core_utils.litellm_logging import (
|
||||
Logging as LiteLLMLoggingObject,
|
||||
)
|
||||
|
|
@ -80,7 +87,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
if output_format:
|
||||
request_data["output_format"] = output_format
|
||||
|
||||
openai_request = ANTHROPIC_ADAPTER.translate_completion_input_params(
|
||||
openai_request, tool_name_mapping = ANTHROPIC_ADAPTER.translate_completion_input_params_with_tool_mapping(
|
||||
request_data
|
||||
)
|
||||
|
||||
|
|
@ -116,7 +123,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
):
|
||||
completion_kwargs[key] = value
|
||||
|
||||
return completion_kwargs
|
||||
return completion_kwargs, tool_name_mapping
|
||||
|
||||
@staticmethod
|
||||
async def async_anthropic_messages_handler(
|
||||
|
|
@ -137,7 +144,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
**kwargs,
|
||||
) -> Union[AnthropicMessagesResponse, AsyncIterator]:
|
||||
"""Handle non-Anthropic models asynchronously using the adapter"""
|
||||
completion_kwargs = (
|
||||
completion_kwargs, tool_name_mapping = (
|
||||
LiteLLMMessagesToCompletionTransformationHandler._prepare_completion_kwargs(
|
||||
max_tokens=max_tokens,
|
||||
messages=messages,
|
||||
|
|
@ -164,6 +171,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
ANTHROPIC_ADAPTER.translate_completion_output_params_streaming(
|
||||
completion_response,
|
||||
model=model,
|
||||
tool_name_mapping=tool_name_mapping,
|
||||
)
|
||||
)
|
||||
if transformed_stream is not None:
|
||||
|
|
@ -172,7 +180,8 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
else:
|
||||
anthropic_response = (
|
||||
ANTHROPIC_ADAPTER.translate_completion_output_params(
|
||||
cast(ModelResponse, completion_response)
|
||||
cast(ModelResponse, completion_response),
|
||||
tool_name_mapping=tool_name_mapping,
|
||||
)
|
||||
)
|
||||
if anthropic_response is not None:
|
||||
|
|
@ -222,7 +231,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
**kwargs,
|
||||
)
|
||||
|
||||
completion_kwargs = (
|
||||
completion_kwargs, tool_name_mapping = (
|
||||
LiteLLMMessagesToCompletionTransformationHandler._prepare_completion_kwargs(
|
||||
max_tokens=max_tokens,
|
||||
messages=messages,
|
||||
|
|
@ -249,6 +258,7 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
ANTHROPIC_ADAPTER.translate_completion_output_params_streaming(
|
||||
completion_response,
|
||||
model=model,
|
||||
tool_name_mapping=tool_name_mapping,
|
||||
)
|
||||
)
|
||||
if transformed_stream is not None:
|
||||
|
|
@ -257,7 +267,8 @@ class LiteLLMMessagesToCompletionTransformationHandler:
|
|||
else:
|
||||
anthropic_response = (
|
||||
ANTHROPIC_ADAPTER.translate_completion_output_params(
|
||||
cast(ModelResponse, completion_response)
|
||||
cast(ModelResponse, completion_response),
|
||||
tool_name_mapping=tool_name_mapping,
|
||||
)
|
||||
)
|
||||
if anthropic_response is not None:
|
||||
|
|
|
|||
|
|
@ -3,7 +3,7 @@
|
|||
import json
|
||||
import traceback
|
||||
from collections import deque
|
||||
from typing import TYPE_CHECKING, Any, AsyncIterator, Iterator, Literal, Optional
|
||||
from typing import TYPE_CHECKING, Any, AsyncIterator, Dict, Iterator, Literal, Optional
|
||||
|
||||
from litellm import verbose_logger
|
||||
from litellm._uuid import uuid
|
||||
|
|
@ -44,9 +44,16 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
|
|||
pending_new_content_block: bool = False
|
||||
chunk_queue: deque = deque() # Queue for buffering multiple chunks
|
||||
|
||||
def __init__(self, completion_stream: Any, model: str):
|
||||
def __init__(
|
||||
self,
|
||||
completion_stream: Any,
|
||||
model: str,
|
||||
tool_name_mapping: Optional[Dict[str, str]] = None,
|
||||
):
|
||||
super().__init__(completion_stream)
|
||||
self.model = model
|
||||
# Mapping of truncated tool names to original names (for OpenAI's 64-char limit)
|
||||
self.tool_name_mapping = tool_name_mapping or {}
|
||||
|
||||
def _create_initial_usage_delta(self) -> UsageDelta:
|
||||
"""
|
||||
|
|
@ -401,6 +408,19 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
|
|||
choices=chunk.choices # type: ignore
|
||||
)
|
||||
|
||||
# Restore original tool name if it was truncated for OpenAI's 64-char limit
|
||||
if block_type == "tool_use":
|
||||
# Type narrowing: content_block_start is ToolUseBlock when block_type is "tool_use"
|
||||
from typing import cast
|
||||
from litellm.types.llms.anthropic import ToolUseBlock
|
||||
|
||||
tool_block = cast(ToolUseBlock, content_block_start)
|
||||
|
||||
if tool_block.get("name"):
|
||||
truncated_name = tool_block["name"]
|
||||
original_name = self.tool_name_mapping.get(truncated_name, truncated_name)
|
||||
tool_block["name"] = original_name
|
||||
|
||||
if block_type != self.current_content_block_type:
|
||||
self.current_content_block_type = block_type
|
||||
self.current_content_block_start = content_block_start
|
||||
|
|
@ -408,9 +428,14 @@ class AnthropicStreamWrapper(AdapterCompletionStreamWrapper):
|
|||
|
||||
# For parallel tool calls, we'll necessarily have a new content block
|
||||
# if we get a function name since it signals a new tool call
|
||||
if block_type == "tool_use" and content_block_start.get("name"):
|
||||
self.current_content_block_type = block_type
|
||||
self.current_content_block_start = content_block_start
|
||||
return True
|
||||
if block_type == "tool_use":
|
||||
from typing import cast
|
||||
from litellm.types.llms.anthropic import ToolUseBlock
|
||||
|
||||
tool_block = cast(ToolUseBlock, content_block_start)
|
||||
if tool_block.get("name"):
|
||||
self.current_content_block_type = block_type
|
||||
self.current_content_block_start = content_block_start
|
||||
return True
|
||||
|
||||
return False
|
||||
|
|
|
|||
|
|
@ -1,3 +1,4 @@
|
|||
import hashlib
|
||||
import json
|
||||
from typing import (
|
||||
TYPE_CHECKING,
|
||||
|
|
@ -12,6 +13,54 @@ from typing import (
|
|||
cast,
|
||||
)
|
||||
|
||||
# OpenAI has a 64-character limit for function/tool names
|
||||
# Anthropic does not have this limit, so we need to truncate long names
|
||||
OPENAI_MAX_TOOL_NAME_LENGTH = 64
|
||||
TOOL_NAME_HASH_LENGTH = 8
|
||||
TOOL_NAME_PREFIX_LENGTH = OPENAI_MAX_TOOL_NAME_LENGTH - TOOL_NAME_HASH_LENGTH - 1 # 55
|
||||
|
||||
|
||||
def truncate_tool_name(name: str) -> str:
|
||||
"""
|
||||
Truncate tool names that exceed OpenAI's 64-character limit.
|
||||
|
||||
Uses format: {55-char-prefix}_{8-char-hash} to avoid collisions
|
||||
when multiple tools have similar long names.
|
||||
|
||||
Args:
|
||||
name: The original tool name
|
||||
|
||||
Returns:
|
||||
The original name if <= 64 chars, otherwise truncated with hash
|
||||
"""
|
||||
if len(name) <= OPENAI_MAX_TOOL_NAME_LENGTH:
|
||||
return name
|
||||
|
||||
# Create deterministic hash from full name to avoid collisions
|
||||
name_hash = hashlib.sha256(name.encode()).hexdigest()[:TOOL_NAME_HASH_LENGTH]
|
||||
return f"{name[:TOOL_NAME_PREFIX_LENGTH]}_{name_hash}"
|
||||
|
||||
|
||||
def create_tool_name_mapping(
|
||||
tools: List[Dict[str, Any]],
|
||||
) -> Dict[str, str]:
|
||||
"""
|
||||
Create a mapping of truncated tool names to original names.
|
||||
|
||||
Args:
|
||||
tools: List of tool definitions with 'name' field
|
||||
|
||||
Returns:
|
||||
Dict mapping truncated names to original names (only for truncated tools)
|
||||
"""
|
||||
mapping: Dict[str, str] = {}
|
||||
for tool in tools:
|
||||
original_name = tool.get("name", "")
|
||||
truncated_name = truncate_tool_name(original_name)
|
||||
if truncated_name != original_name:
|
||||
mapping[truncated_name] = original_name
|
||||
return mapping
|
||||
|
||||
from openai.types.chat.chat_completion_chunk import Choice as OpenAIStreamingChoice
|
||||
|
||||
from litellm.litellm_core_utils.prompt_templates.common_utils import (
|
||||
|
|
@ -77,8 +126,29 @@ class AnthropicAdapter:
|
|||
self, kwargs
|
||||
) -> Optional[ChatCompletionRequest]:
|
||||
"""
|
||||
Translate Anthropic request params to OpenAI format.
|
||||
|
||||
- translate params, where needed
|
||||
- pass rest, as is
|
||||
|
||||
Note: Use translate_completion_input_params_with_tool_mapping() if you need
|
||||
the tool name mapping for restoring original names in responses.
|
||||
"""
|
||||
result, _ = self.translate_completion_input_params_with_tool_mapping(kwargs)
|
||||
return result
|
||||
|
||||
def translate_completion_input_params_with_tool_mapping(
|
||||
self, kwargs
|
||||
) -> Tuple[Optional[ChatCompletionRequest], Dict[str, str]]:
|
||||
"""
|
||||
Translate Anthropic request params to OpenAI format, returning tool name mapping.
|
||||
|
||||
This method handles truncation of tool names that exceed OpenAI's 64-character
|
||||
limit. The mapping allows restoring original names when translating responses.
|
||||
|
||||
Returns:
|
||||
Tuple of (openai_request, tool_name_mapping)
|
||||
- tool_name_mapping maps truncated tool names back to original names
|
||||
"""
|
||||
|
||||
#########################################################
|
||||
|
|
@ -102,26 +172,51 @@ class AnthropicAdapter:
|
|||
model=model, messages=messages, **kwargs
|
||||
)
|
||||
|
||||
translated_body = (
|
||||
translated_body, tool_name_mapping = (
|
||||
LiteLLMAnthropicMessagesAdapter().translate_anthropic_to_openai(
|
||||
anthropic_message_request=request_body
|
||||
)
|
||||
)
|
||||
|
||||
return translated_body
|
||||
return translated_body, tool_name_mapping
|
||||
|
||||
def translate_completion_output_params(
|
||||
self, response: ModelResponse
|
||||
self,
|
||||
response: ModelResponse,
|
||||
tool_name_mapping: Optional[Dict[str, str]] = None,
|
||||
) -> Optional[AnthropicMessagesResponse]:
|
||||
"""
|
||||
Translate OpenAI response to Anthropic format.
|
||||
|
||||
Args:
|
||||
response: The OpenAI ModelResponse
|
||||
tool_name_mapping: Optional mapping of truncated tool names to original names.
|
||||
Used to restore original names for tools that exceeded
|
||||
OpenAI's 64-char limit.
|
||||
"""
|
||||
return LiteLLMAnthropicMessagesAdapter().translate_openai_response_to_anthropic(
|
||||
response=response
|
||||
response=response,
|
||||
tool_name_mapping=tool_name_mapping,
|
||||
)
|
||||
|
||||
def translate_completion_output_params_streaming(
|
||||
self, completion_stream: Any, model: str
|
||||
self,
|
||||
completion_stream: Any,
|
||||
model: str,
|
||||
tool_name_mapping: Optional[Dict[str, str]] = None,
|
||||
) -> Union[AsyncIterator[bytes], None]:
|
||||
"""
|
||||
Translate OpenAI streaming response to Anthropic format.
|
||||
|
||||
Args:
|
||||
completion_stream: The OpenAI streaming response
|
||||
model: The model name
|
||||
tool_name_mapping: Optional mapping of truncated tool names to original names.
|
||||
"""
|
||||
anthropic_wrapper = AnthropicStreamWrapper(
|
||||
completion_stream=completion_stream, model=model
|
||||
completion_stream=completion_stream,
|
||||
model=model,
|
||||
tool_name_mapping=tool_name_mapping,
|
||||
)
|
||||
# Return the SSE-wrapped version for proper event formatting
|
||||
return anthropic_wrapper.async_anthropic_sse_wrapper()
|
||||
|
|
@ -417,8 +512,10 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
has_cache_control_in_text = True
|
||||
assistant_content_list.append(text_block)
|
||||
elif content.get("type") == "tool_use":
|
||||
# Truncate tool name for OpenAI's 64-char limit
|
||||
tool_name = truncate_tool_name(content.get("name", ""))
|
||||
function_chunk: ChatCompletionToolCallFunctionChunk = {
|
||||
"name": content.get("name", ""),
|
||||
"name": tool_name,
|
||||
"arguments": json.dumps(content.get("input", {})),
|
||||
}
|
||||
signature = (
|
||||
|
|
@ -587,8 +684,11 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
elif tool_choice["type"] == "auto":
|
||||
return "auto"
|
||||
elif tool_choice["type"] == "tool":
|
||||
# Truncate tool name if it exceeds OpenAI's 64-char limit
|
||||
original_name = tool_choice.get("name", "")
|
||||
truncated_name = truncate_tool_name(original_name)
|
||||
tc_function_param = ChatCompletionToolChoiceFunctionParam(
|
||||
name=tool_choice.get("name", "")
|
||||
name=truncated_name
|
||||
)
|
||||
return ChatCompletionToolChoiceObjectParam(
|
||||
type="function", function=tc_function_param
|
||||
|
|
@ -600,12 +700,28 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
|
||||
def translate_anthropic_tools_to_openai(
|
||||
self, tools: List[AllAnthropicToolsValues], model: Optional[str] = None
|
||||
) -> List[ChatCompletionToolParam]:
|
||||
) -> Tuple[List[ChatCompletionToolParam], Dict[str, str]]:
|
||||
"""
|
||||
Translate Anthropic tools to OpenAI format.
|
||||
|
||||
Returns:
|
||||
Tuple of (translated_tools, tool_name_mapping)
|
||||
- tool_name_mapping maps truncated names back to original names
|
||||
for tools that exceeded OpenAI's 64-char limit
|
||||
"""
|
||||
new_tools: List[ChatCompletionToolParam] = []
|
||||
tool_name_mapping: Dict[str, str] = {}
|
||||
mapped_tool_params = ["name", "input_schema", "description", "cache_control"]
|
||||
for tool in tools:
|
||||
original_name = tool["name"]
|
||||
truncated_name = truncate_tool_name(original_name)
|
||||
|
||||
# Store mapping if name was truncated
|
||||
if truncated_name != original_name:
|
||||
tool_name_mapping[truncated_name] = original_name
|
||||
|
||||
function_chunk = ChatCompletionToolParamFunctionChunk(
|
||||
name=tool["name"],
|
||||
name=truncated_name,
|
||||
)
|
||||
if "input_schema" in tool:
|
||||
function_chunk["parameters"] = tool["input_schema"] # type: ignore
|
||||
|
|
@ -619,7 +735,7 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
self._add_cache_control_if_applicable(tool, tool_param, model)
|
||||
new_tools.append(tool_param) # type: ignore[arg-type]
|
||||
|
||||
return new_tools # type: ignore[return-value]
|
||||
return new_tools, tool_name_mapping # type: ignore[return-value]
|
||||
|
||||
def translate_anthropic_output_format_to_openai(
|
||||
self, output_format: Any
|
||||
|
|
@ -694,12 +810,18 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
|
||||
def translate_anthropic_to_openai(
|
||||
self, anthropic_message_request: AnthropicMessagesRequest
|
||||
) -> ChatCompletionRequest:
|
||||
) -> Tuple[ChatCompletionRequest, Dict[str, str]]:
|
||||
"""
|
||||
This is used by the beta Anthropic Adapter, for translating anthropic `/v1/messages` requests to the openai format.
|
||||
|
||||
Returns:
|
||||
Tuple of (openai_request, tool_name_mapping)
|
||||
- tool_name_mapping maps truncated tool names back to original names
|
||||
for tools that exceeded OpenAI's 64-char limit
|
||||
"""
|
||||
# Debug: Processing Anthropic message request
|
||||
new_messages: List[AllMessageValues] = []
|
||||
tool_name_mapping: Dict[str, str] = {}
|
||||
|
||||
## CONVERT ANTHROPIC MESSAGES TO OPENAI
|
||||
messages_list: List[
|
||||
|
|
@ -750,7 +872,7 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
if "tools" in anthropic_message_request:
|
||||
tools = anthropic_message_request["tools"]
|
||||
if tools:
|
||||
new_kwargs["tools"] = self.translate_anthropic_tools_to_openai(
|
||||
new_kwargs["tools"], tool_name_mapping = self.translate_anthropic_tools_to_openai(
|
||||
tools=cast(List[AllAnthropicToolsValues], tools),
|
||||
model=new_kwargs.get("model"),
|
||||
)
|
||||
|
|
@ -784,7 +906,7 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
if k not in translatable_params: # pass remaining params as is
|
||||
new_kwargs[k] = v # type: ignore
|
||||
|
||||
return new_kwargs
|
||||
return new_kwargs, tool_name_mapping
|
||||
|
||||
def _translate_anthropic_image_to_openai(self, image_source: dict) -> Optional[str]:
|
||||
"""
|
||||
|
|
@ -813,7 +935,11 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
|
||||
return None
|
||||
|
||||
def _translate_openai_content_to_anthropic(self, choices: List[Choices]) -> List[
|
||||
def _translate_openai_content_to_anthropic(
|
||||
self,
|
||||
choices: List[Choices],
|
||||
tool_name_mapping: Optional[Dict[str, str]] = None,
|
||||
) -> List[
|
||||
Union[
|
||||
AnthropicResponseContentBlockText,
|
||||
AnthropicResponseContentBlockToolUse,
|
||||
|
|
@ -862,6 +988,18 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
data=str(data_value) if data_value is not None else "",
|
||||
)
|
||||
)
|
||||
# Handle reasoning_content when thinking_blocks is not present
|
||||
elif (
|
||||
hasattr(choice.message, "reasoning_content")
|
||||
and choice.message.reasoning_content
|
||||
):
|
||||
new_content.append(
|
||||
AnthropicResponseContentBlockThinking(
|
||||
type="thinking",
|
||||
thinking=str(choice.message.reasoning_content),
|
||||
signature=None,
|
||||
)
|
||||
)
|
||||
|
||||
# Handle text content
|
||||
if choice.message.content is not None:
|
||||
|
|
@ -883,13 +1021,21 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
if signature:
|
||||
provider_specific_fields["signature"] = signature
|
||||
|
||||
# Restore original tool name if it was truncated
|
||||
truncated_name = tool_call.function.name or ""
|
||||
original_name = (
|
||||
tool_name_mapping.get(truncated_name, truncated_name)
|
||||
if tool_name_mapping
|
||||
else truncated_name
|
||||
)
|
||||
|
||||
tool_use_block = AnthropicResponseContentBlockToolUse(
|
||||
type="tool_use",
|
||||
id=tool_call.id,
|
||||
name=tool_call.function.name or "",
|
||||
name=original_name,
|
||||
input=parse_tool_call_arguments(
|
||||
tool_call.function.arguments,
|
||||
tool_name=tool_call.function.name,
|
||||
tool_name=original_name,
|
||||
context="Anthropic pass-through adapter",
|
||||
),
|
||||
)
|
||||
|
|
@ -914,10 +1060,24 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
return "end_turn"
|
||||
|
||||
def translate_openai_response_to_anthropic(
|
||||
self, response: ModelResponse
|
||||
self,
|
||||
response: ModelResponse,
|
||||
tool_name_mapping: Optional[Dict[str, str]] = None,
|
||||
) -> AnthropicMessagesResponse:
|
||||
"""
|
||||
Translate OpenAI response to Anthropic format.
|
||||
|
||||
Args:
|
||||
response: The OpenAI ModelResponse
|
||||
tool_name_mapping: Optional mapping of truncated tool names to original names.
|
||||
Used to restore original names for tools that exceeded
|
||||
OpenAI's 64-char limit.
|
||||
"""
|
||||
## translate content block
|
||||
anthropic_content = self._translate_openai_content_to_anthropic(choices=response.choices) # type: ignore
|
||||
anthropic_content = self._translate_openai_content_to_anthropic(
|
||||
choices=response.choices, # type: ignore
|
||||
tool_name_mapping=tool_name_mapping,
|
||||
)
|
||||
## extract finish reason
|
||||
anthropic_finish_reason = self._translate_openai_finish_reason_to_anthropic(
|
||||
openai_finish_reason=response.choices[0].finish_reason # type: ignore
|
||||
|
|
@ -1036,6 +1196,13 @@ class LiteLLMAnthropicMessagesAdapter:
|
|||
|
||||
reasoning_content += thinking
|
||||
reasoning_signature += signature
|
||||
# Handle reasoning_content when thinking_blocks is not present
|
||||
# This handles providers like OpenRouter that return reasoning_content
|
||||
elif isinstance(choice, StreamingChoices) and hasattr(
|
||||
choice.delta, "reasoning_content"
|
||||
):
|
||||
if choice.delta.reasoning_content is not None:
|
||||
reasoning_content += choice.delta.reasoning_content
|
||||
|
||||
if reasoning_content and reasoning_signature:
|
||||
raise ValueError(
|
||||
|
|
|
|||
|
|
@ -30,30 +30,32 @@ class AzureAIAnthropicCountTokensConfig(AnthropicCountTokensConfig):
|
|||
"""
|
||||
Get the required headers for the Azure AI Anthropic CountTokens API.
|
||||
|
||||
Uses Azure authentication (api-key header) instead of Anthropic's x-api-key.
|
||||
Azure AI Anthropic uses Anthropic's native API format, which requires the
|
||||
x-api-key header for authentication (in addition to Azure's api-key header).
|
||||
|
||||
Args:
|
||||
api_key: The Azure AI API key
|
||||
litellm_params: Optional LiteLLM parameters for additional auth config
|
||||
|
||||
Returns:
|
||||
Dictionary of required headers with Azure authentication
|
||||
Dictionary of required headers with both x-api-key and Azure authentication
|
||||
"""
|
||||
# Start with base headers
|
||||
# Start with base headers including x-api-key for Anthropic API compatibility
|
||||
headers = {
|
||||
"Content-Type": "application/json",
|
||||
"anthropic-version": "2023-06-01",
|
||||
"anthropic-beta": ANTHROPIC_TOKEN_COUNTING_BETA_VERSION,
|
||||
"x-api-key": api_key, # Azure AI Anthropic requires this header
|
||||
}
|
||||
|
||||
# Use Azure authentication
|
||||
# Also set up Azure auth headers for flexibility
|
||||
litellm_params = litellm_params or {}
|
||||
if "api_key" not in litellm_params:
|
||||
litellm_params["api_key"] = api_key
|
||||
|
||||
litellm_params_obj = GenericLiteLLMParams(**litellm_params)
|
||||
|
||||
# Get Azure auth headers
|
||||
# Get Azure auth headers (api-key or Authorization)
|
||||
azure_headers = BaseAzureLLM._base_validate_azure_environment(
|
||||
headers={}, litellm_params=litellm_params_obj
|
||||
)
|
||||
|
|
@ -68,7 +70,7 @@ class AzureAIAnthropicCountTokensConfig(AnthropicCountTokensConfig):
|
|||
Get the Azure AI Anthropic CountTokens API endpoint.
|
||||
|
||||
Args:
|
||||
api_base: The Azure AI API base URL
|
||||
api_base: The Azure AI API base URL
|
||||
(e.g., https://my-resource.services.ai.azure.com or
|
||||
https://my-resource.services.ai.azure.com/anthropic)
|
||||
|
||||
|
|
|
|||
|
|
@ -21,12 +21,19 @@ class AzureFoundryModelInfo(BaseLLMModelInfo):
|
|||
|
||||
Supported routes:
|
||||
- agents: azure_ai/agents/<agent_id>
|
||||
- model_router: azure_ai/model_router/<actual-model-name>
|
||||
- model_router: azure_ai/model_router/<actual-model-name> or models with "model-router"/"model_router" in name
|
||||
- default: standard models
|
||||
"""
|
||||
if "agents/" in model:
|
||||
return "agents"
|
||||
if "model_router/" in model or "model-router/" in model:
|
||||
# Detect model router by prefix (model_router/<name>) or by name containing "model-router"/"model_router"
|
||||
model_lower = model.lower()
|
||||
if (
|
||||
"model_router/" in model_lower
|
||||
or "model-router/" in model_lower
|
||||
or "model-router" in model_lower
|
||||
or "model_router" in model_lower
|
||||
):
|
||||
return "model_router"
|
||||
return "default"
|
||||
|
||||
|
|
|
|||
|
|
@ -77,16 +77,35 @@ def cost_per_token(
|
|||
|
||||
Returns:
|
||||
Tuple[float, float] - prompt_cost_in_usd, completion_cost_in_usd
|
||||
|
||||
Raises:
|
||||
ValueError: If the model is not found in the cost map and cost cannot be calculated
|
||||
(except for Model Router models where we return just the routing flat cost)
|
||||
"""
|
||||
prompt_cost = 0.0
|
||||
completion_cost = 0.0
|
||||
|
||||
# Calculate base cost using generic cost calculator
|
||||
prompt_cost, completion_cost = generic_cost_per_token(
|
||||
model=model,
|
||||
usage=usage,
|
||||
custom_llm_provider="azure_ai",
|
||||
)
|
||||
# This may raise an exception if the model is not in the cost map
|
||||
try:
|
||||
prompt_cost, completion_cost = generic_cost_per_token(
|
||||
model=model,
|
||||
usage=usage,
|
||||
custom_llm_provider="azure_ai",
|
||||
)
|
||||
except Exception as e:
|
||||
# For Model Router, the model name (e.g., "azure-model-router") may not be in the cost map
|
||||
# because it's a routing service, not an actual model. In this case, we continue
|
||||
# to calculate just the routing flat cost.
|
||||
if not _is_azure_model_router(model):
|
||||
# Re-raise for non-router models - they should have pricing defined
|
||||
raise
|
||||
verbose_logger.debug(
|
||||
f"Azure AI Model Router: model '{model}' not in cost map, calculating routing flat cost only. Error: {e}"
|
||||
)
|
||||
|
||||
# Add flat cost for Azure Model Router
|
||||
# The flat cost is defined in model_prices_and_context_window.json for azure_ai/azure-model-router
|
||||
# The flat cost is defined in model_prices_and_context_window.json for azure_ai/model_router
|
||||
if _is_azure_model_router(model):
|
||||
router_flat_cost = calculate_azure_model_router_flat_cost(model, usage.prompt_tokens)
|
||||
|
||||
|
|
|
|||
|
|
@ -11,6 +11,7 @@ from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLogging
|
|||
from litellm.llms.cohere.rerank.transformation import CohereRerankConfig
|
||||
from litellm.secret_managers.main import get_secret_str
|
||||
from litellm.types.utils import RerankResponse
|
||||
from litellm.utils import _add_path_to_api_base
|
||||
|
||||
|
||||
class AzureAIRerankConfig(CohereRerankConfig):
|
||||
|
|
@ -28,9 +29,34 @@ class AzureAIRerankConfig(CohereRerankConfig):
|
|||
raise ValueError(
|
||||
"Azure AI API Base is required. api_base=None. Set in call or via `AZURE_AI_API_BASE` env var."
|
||||
)
|
||||
if not api_base.endswith("/v1/rerank"):
|
||||
api_base = f"{api_base}/v1/rerank"
|
||||
return api_base
|
||||
original_url = httpx.URL(api_base)
|
||||
if not original_url.is_absolute_url:
|
||||
raise ValueError(
|
||||
"Azure AI API Base must be an absolute URL including scheme (e.g. "
|
||||
"'https://<resource>.services.ai.azure.com'). "
|
||||
f"Got api_base={api_base!r}."
|
||||
)
|
||||
normalized_path = original_url.path.rstrip("/")
|
||||
|
||||
# Allow callers to pass either full v1/v2 rerank endpoints:
|
||||
# - https://<resource>.services.ai.azure.com/v1/rerank
|
||||
# - https://<resource>.services.ai.azure.com/providers/cohere/v2/rerank
|
||||
if normalized_path.endswith("/v1/rerank") or normalized_path.endswith("/v2/rerank"):
|
||||
return str(original_url.copy_with(path=normalized_path or "/"))
|
||||
|
||||
# If callers pass just the version path (e.g. ".../v2" or ".../providers/cohere/v2"), append "/rerank"
|
||||
if (
|
||||
normalized_path.endswith("/v1")
|
||||
or normalized_path.endswith("/v2")
|
||||
or normalized_path.endswith("/providers/cohere/v2")
|
||||
):
|
||||
return _add_path_to_api_base(
|
||||
api_base=str(original_url.copy_with(path=normalized_path or "/")),
|
||||
ending_path="/rerank",
|
||||
)
|
||||
|
||||
# Backwards compatible default: Azure AI rerank was originally exposed under /v1/rerank
|
||||
return _add_path_to_api_base(api_base=api_base, ending_path="/v1/rerank")
|
||||
|
||||
def validate_environment(
|
||||
self,
|
||||
|
|
|
|||
|
|
@ -805,7 +805,9 @@ class AmazonConverseConfig(BaseConfig):
|
|||
if bedrock_tier in ("default", "flex", "priority"):
|
||||
optional_params["serviceTier"] = {"type": bedrock_tier}
|
||||
|
||||
if param == "web_search_options" and value and isinstance(value, dict):
|
||||
if param == "web_search_options" and isinstance(value, dict):
|
||||
# Note: we use `isinstance(value, dict)` instead of `value and isinstance(value, dict)`
|
||||
# because empty dict {} is falsy but is a valid way to enable Nova grounding
|
||||
grounding_tool = self._map_web_search_options(value, model)
|
||||
if grounding_tool is not None:
|
||||
optional_params = self._add_tools_to_optional_params(
|
||||
|
|
@ -1079,10 +1081,16 @@ class AmazonConverseConfig(BaseConfig):
|
|||
user_betas = get_anthropic_beta_from_headers(headers)
|
||||
anthropic_beta_list.extend(user_betas)
|
||||
|
||||
# Filter out tool search tools - Bedrock Converse API doesn't support them
|
||||
# Separate pre-formatted Bedrock tools (e.g. systemTool from web_search_options)
|
||||
# from OpenAI-format tools that need transformation via _bedrock_tools_pt
|
||||
filtered_tools = []
|
||||
pre_formatted_tools: List[ToolBlock] = []
|
||||
if original_tools:
|
||||
for tool in original_tools:
|
||||
# Already-formatted Bedrock tools (e.g. systemTool for Nova grounding)
|
||||
if "systemTool" in tool:
|
||||
pre_formatted_tools.append(tool)
|
||||
continue
|
||||
tool_type = tool.get("type", "")
|
||||
if tool_type in (
|
||||
"tool_search_tool_regex_20251119",
|
||||
|
|
@ -1114,6 +1122,9 @@ class AmazonConverseConfig(BaseConfig):
|
|||
# No computer use tools, process all tools as regular tools
|
||||
bedrock_tools = _bedrock_tools_pt(filtered_tools)
|
||||
|
||||
# Append pre-formatted tools (systemTool etc.) after transformation
|
||||
bedrock_tools.extend(pre_formatted_tools)
|
||||
|
||||
# Set anthropic_beta in additional_request_params if we have any beta features
|
||||
# ONLY apply to Anthropic/Claude models - other models (e.g., Qwen, Llama) don't support this field
|
||||
# and will error with "unknown variant anthropic_beta" if included
|
||||
|
|
|
|||
|
|
@ -15,7 +15,7 @@ class BedrockCohereEmbeddingConfig:
|
|||
pass
|
||||
|
||||
def get_supported_openai_params(self) -> List[str]:
|
||||
return ["encoding_format"]
|
||||
return ["encoding_format", "dimensions"]
|
||||
|
||||
def map_openai_params(
|
||||
self, non_default_params: dict, optional_params: dict
|
||||
|
|
@ -23,6 +23,8 @@ class BedrockCohereEmbeddingConfig:
|
|||
for k, v in non_default_params.items():
|
||||
if k == "encoding_format":
|
||||
optional_params["embedding_types"] = v
|
||||
elif k == "dimensions":
|
||||
optional_params["output_dimension"] = v
|
||||
return optional_params
|
||||
|
||||
def _is_v3_model(self, model: str) -> bool:
|
||||
|
|
|
|||
307
litellm/llms/bedrock/realtime/handler.py
Normal file
307
litellm/llms/bedrock/realtime/handler.py
Normal file
|
|
@ -0,0 +1,307 @@
|
|||
"""
|
||||
This file contains the handler for AWS Bedrock Nova Sonic realtime API.
|
||||
|
||||
This uses aws_sdk_bedrock_runtime for bidirectional streaming with Nova Sonic.
|
||||
"""
|
||||
|
||||
import asyncio
|
||||
import json
|
||||
from typing import Any, Optional
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLogging
|
||||
|
||||
from ..base_aws_llm import BaseAWSLLM
|
||||
from .transformation import BedrockRealtimeConfig
|
||||
|
||||
|
||||
class BedrockRealtime(BaseAWSLLM):
|
||||
"""Handler for Bedrock Nova Sonic realtime speech-to-speech API."""
|
||||
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
|
||||
async def async_realtime(
|
||||
self,
|
||||
model: str,
|
||||
websocket: Any,
|
||||
logging_obj: LiteLLMLogging,
|
||||
api_base: Optional[str] = None,
|
||||
api_key: Optional[str] = None,
|
||||
timeout: Optional[float] = None,
|
||||
aws_region_name: Optional[str] = None,
|
||||
aws_access_key_id: Optional[str] = None,
|
||||
aws_secret_access_key: Optional[str] = None,
|
||||
aws_session_token: Optional[str] = None,
|
||||
aws_role_name: Optional[str] = None,
|
||||
aws_session_name: Optional[str] = None,
|
||||
aws_profile_name: Optional[str] = None,
|
||||
aws_web_identity_token: Optional[str] = None,
|
||||
aws_sts_endpoint: Optional[str] = None,
|
||||
aws_bedrock_runtime_endpoint: Optional[str] = None,
|
||||
aws_external_id: Optional[str] = None,
|
||||
**kwargs,
|
||||
):
|
||||
"""
|
||||
Establish bidirectional streaming connection with Bedrock Nova Sonic.
|
||||
|
||||
Args:
|
||||
model: Model ID (e.g., 'amazon.nova-sonic-v1:0')
|
||||
websocket: Client WebSocket connection
|
||||
logging_obj: LiteLLM logging object
|
||||
aws_region_name: AWS region
|
||||
Various AWS authentication parameters
|
||||
"""
|
||||
try:
|
||||
from aws_sdk_bedrock_runtime.client import (
|
||||
BedrockRuntimeClient,
|
||||
InvokeModelWithBidirectionalStreamOperationInput,
|
||||
)
|
||||
from aws_sdk_bedrock_runtime.config import Config
|
||||
from smithy_aws_core.identity.environment import (
|
||||
EnvironmentCredentialsResolver,
|
||||
)
|
||||
except ImportError:
|
||||
raise ImportError(
|
||||
"Missing aws_sdk_bedrock_runtime. Install with: pip install aws-sdk-bedrock-runtime"
|
||||
)
|
||||
|
||||
# Get AWS region
|
||||
if aws_region_name is None:
|
||||
optional_params = {
|
||||
"aws_region_name": aws_region_name,
|
||||
}
|
||||
aws_region_name = self._get_aws_region_name(optional_params, model)
|
||||
|
||||
# Get endpoint URL
|
||||
if api_base is not None:
|
||||
endpoint_uri = api_base
|
||||
elif aws_bedrock_runtime_endpoint is not None:
|
||||
endpoint_uri = aws_bedrock_runtime_endpoint
|
||||
else:
|
||||
endpoint_uri = f"https://bedrock-runtime.{aws_region_name}.amazonaws.com"
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
f"Bedrock Realtime: Connecting to {endpoint_uri} with model {model}"
|
||||
)
|
||||
|
||||
# Initialize Bedrock client with aws_sdk_bedrock_runtime
|
||||
config = Config(
|
||||
endpoint_uri=endpoint_uri,
|
||||
region=aws_region_name,
|
||||
aws_credentials_identity_resolver=EnvironmentCredentialsResolver(),
|
||||
)
|
||||
bedrock_client = BedrockRuntimeClient(config=config)
|
||||
|
||||
transformation_config = BedrockRealtimeConfig()
|
||||
|
||||
try:
|
||||
# Initialize the bidirectional stream
|
||||
bedrock_stream = await bedrock_client.invoke_model_with_bidirectional_stream(
|
||||
InvokeModelWithBidirectionalStreamOperationInput(model_id=model)
|
||||
)
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
"Bedrock Realtime: Bidirectional stream established"
|
||||
)
|
||||
|
||||
# Track state for transformation
|
||||
session_state = {
|
||||
"current_output_item_id": None,
|
||||
"current_response_id": None,
|
||||
"current_conversation_id": None,
|
||||
"current_delta_chunks": None,
|
||||
"current_item_chunks": None,
|
||||
"current_delta_type": None,
|
||||
"session_configuration_request": None,
|
||||
}
|
||||
|
||||
# Create tasks for bidirectional forwarding
|
||||
client_to_bedrock_task = asyncio.create_task(
|
||||
self._forward_client_to_bedrock(
|
||||
websocket,
|
||||
bedrock_stream,
|
||||
transformation_config,
|
||||
model,
|
||||
session_state,
|
||||
)
|
||||
)
|
||||
|
||||
bedrock_to_client_task = asyncio.create_task(
|
||||
self._forward_bedrock_to_client(
|
||||
bedrock_stream,
|
||||
websocket,
|
||||
transformation_config,
|
||||
model,
|
||||
logging_obj,
|
||||
session_state,
|
||||
)
|
||||
)
|
||||
|
||||
# Wait for both tasks to complete
|
||||
await asyncio.gather(
|
||||
client_to_bedrock_task,
|
||||
bedrock_to_client_task,
|
||||
return_exceptions=True,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.exception(
|
||||
f"Error in BedrockRealtime.async_realtime: {e}"
|
||||
)
|
||||
try:
|
||||
await websocket.close(code=1011, reason=f"Internal error: {str(e)}")
|
||||
except Exception:
|
||||
pass
|
||||
raise
|
||||
|
||||
async def _forward_client_to_bedrock(
|
||||
self,
|
||||
client_ws: Any,
|
||||
bedrock_stream: Any,
|
||||
transformation_config: BedrockRealtimeConfig,
|
||||
model: str,
|
||||
session_state: dict,
|
||||
):
|
||||
"""Forward messages from client WebSocket to Bedrock stream."""
|
||||
try:
|
||||
from aws_sdk_bedrock_runtime.models import (
|
||||
BidirectionalInputPayloadPart,
|
||||
InvokeModelWithBidirectionalStreamInputChunk,
|
||||
)
|
||||
|
||||
while True:
|
||||
# Receive message from client
|
||||
message = await client_ws.receive_text()
|
||||
verbose_proxy_logger.debug(
|
||||
f"Bedrock Realtime: Received from client: {message[:200]}"
|
||||
)
|
||||
|
||||
# Transform OpenAI format to Bedrock format
|
||||
transformed_messages = transformation_config.transform_realtime_request(
|
||||
message=message,
|
||||
model=model,
|
||||
session_configuration_request=session_state.get(
|
||||
"session_configuration_request"
|
||||
),
|
||||
)
|
||||
|
||||
# Send transformed messages to Bedrock
|
||||
for bedrock_message in transformed_messages:
|
||||
event = InvokeModelWithBidirectionalStreamInputChunk(
|
||||
value=BidirectionalInputPayloadPart(
|
||||
bytes_=bedrock_message.encode("utf-8")
|
||||
)
|
||||
)
|
||||
await bedrock_stream.input_stream.send(event)
|
||||
verbose_proxy_logger.debug(
|
||||
f"Bedrock Realtime: Sent to Bedrock: {bedrock_message[:200]}"
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.debug(
|
||||
f"Client to Bedrock forwarding ended: {e}", exc_info=True
|
||||
)
|
||||
# Close the Bedrock stream input
|
||||
try:
|
||||
await bedrock_stream.input_stream.close()
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
async def _forward_bedrock_to_client(
|
||||
self,
|
||||
bedrock_stream: Any,
|
||||
client_ws: Any,
|
||||
transformation_config: BedrockRealtimeConfig,
|
||||
model: str,
|
||||
logging_obj: LiteLLMLogging,
|
||||
session_state: dict,
|
||||
):
|
||||
"""Forward messages from Bedrock stream to client WebSocket."""
|
||||
try:
|
||||
while True:
|
||||
# Receive from Bedrock
|
||||
output = await bedrock_stream.await_output()
|
||||
result = await output[1].receive()
|
||||
|
||||
if result.value and result.value.bytes_:
|
||||
bedrock_response = result.value.bytes_.decode("utf-8")
|
||||
verbose_proxy_logger.debug(
|
||||
f"Bedrock Realtime: Received from Bedrock: {bedrock_response[:200]}"
|
||||
)
|
||||
|
||||
# Transform Bedrock format to OpenAI format
|
||||
from litellm.types.realtime import RealtimeResponseTransformInput
|
||||
|
||||
realtime_response_transform_input: RealtimeResponseTransformInput = {
|
||||
"current_output_item_id": session_state.get(
|
||||
"current_output_item_id"
|
||||
),
|
||||
"current_response_id": session_state.get("current_response_id"),
|
||||
"current_conversation_id": session_state.get(
|
||||
"current_conversation_id"
|
||||
),
|
||||
"current_delta_chunks": session_state.get(
|
||||
"current_delta_chunks"
|
||||
),
|
||||
"current_item_chunks": session_state.get("current_item_chunks"),
|
||||
"current_delta_type": session_state.get("current_delta_type"),
|
||||
"session_configuration_request": session_state.get(
|
||||
"session_configuration_request"
|
||||
),
|
||||
}
|
||||
|
||||
transformed_response = (
|
||||
transformation_config.transform_realtime_response(
|
||||
message=bedrock_response,
|
||||
model=model,
|
||||
logging_obj=logging_obj,
|
||||
realtime_response_transform_input=realtime_response_transform_input,
|
||||
)
|
||||
)
|
||||
|
||||
# Update session state
|
||||
session_state.update(
|
||||
{
|
||||
"current_output_item_id": transformed_response.get(
|
||||
"current_output_item_id"
|
||||
),
|
||||
"current_response_id": transformed_response.get(
|
||||
"current_response_id"
|
||||
),
|
||||
"current_conversation_id": transformed_response.get(
|
||||
"current_conversation_id"
|
||||
),
|
||||
"current_delta_chunks": transformed_response.get(
|
||||
"current_delta_chunks"
|
||||
),
|
||||
"current_item_chunks": transformed_response.get(
|
||||
"current_item_chunks"
|
||||
),
|
||||
"current_delta_type": transformed_response.get(
|
||||
"current_delta_type"
|
||||
),
|
||||
"session_configuration_request": transformed_response.get(
|
||||
"session_configuration_request"
|
||||
),
|
||||
}
|
||||
)
|
||||
|
||||
# Send transformed messages to client
|
||||
openai_messages = transformed_response.get("response", [])
|
||||
for openai_message in openai_messages:
|
||||
message_json = json.dumps(openai_message)
|
||||
await client_ws.send_text(message_json)
|
||||
verbose_proxy_logger.debug(
|
||||
f"Bedrock Realtime: Sent to client: {message_json[:200]}"
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.debug(
|
||||
f"Bedrock to client forwarding ended: {e}", exc_info=True
|
||||
)
|
||||
# Close the client WebSocket
|
||||
try:
|
||||
await client_ws.close()
|
||||
except Exception:
|
||||
pass
|
||||
1156
litellm/llms/bedrock/realtime/transformation.py
Normal file
1156
litellm/llms/bedrock/realtime/transformation.py
Normal file
File diff suppressed because it is too large
Load diff
|
|
@ -7,6 +7,7 @@ this is OpenAI compatible - no translation needed / occurs
|
|||
from typing import Optional
|
||||
|
||||
from litellm.llms.openai.chat.gpt_transformation import OpenAIGPTConfig
|
||||
from litellm.utils import supports_reasoning
|
||||
|
||||
|
||||
class CerebrasConfig(OpenAIGPTConfig):
|
||||
|
|
@ -24,6 +25,7 @@ class CerebrasConfig(OpenAIGPTConfig):
|
|||
tool_choice: Optional[str] = None
|
||||
tools: Optional[list] = None
|
||||
user: Optional[str] = None
|
||||
reasoning_effort: Optional[str] = None
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
|
|
@ -37,6 +39,7 @@ class CerebrasConfig(OpenAIGPTConfig):
|
|||
tool_choice: Optional[str] = None,
|
||||
tools: Optional[list] = None,
|
||||
user: Optional[str] = None,
|
||||
reasoning_effort: Optional[str] = None,
|
||||
) -> None:
|
||||
locals_ = locals().copy()
|
||||
for key, value in locals_.items():
|
||||
|
|
@ -53,7 +56,7 @@ class CerebrasConfig(OpenAIGPTConfig):
|
|||
|
||||
"""
|
||||
|
||||
return [
|
||||
supported_params = [
|
||||
"max_tokens",
|
||||
"max_completion_tokens",
|
||||
"response_format",
|
||||
|
|
@ -67,6 +70,12 @@ class CerebrasConfig(OpenAIGPTConfig):
|
|||
"user",
|
||||
]
|
||||
|
||||
# Only add reasoning_effort for models that support it
|
||||
if supports_reasoning(model=model, custom_llm_provider="cerebras"):
|
||||
supported_params.append("reasoning_effort")
|
||||
|
||||
return supported_params
|
||||
|
||||
def map_openai_params(
|
||||
self,
|
||||
non_default_params: dict,
|
||||
|
|
|
|||
|
|
@ -50,9 +50,21 @@ try:
|
|||
except Exception:
|
||||
version = "0.0.0"
|
||||
|
||||
headers = {
|
||||
"User-Agent": f"litellm/{version}",
|
||||
}
|
||||
def get_default_headers() -> dict:
|
||||
"""
|
||||
Get default headers for HTTP requests.
|
||||
|
||||
- Default: `User-Agent: litellm/{version}`
|
||||
- Override: set `LITELLM_USER_AGENT` to fully override the header value.
|
||||
"""
|
||||
user_agent = os.environ.get("LITELLM_USER_AGENT")
|
||||
if user_agent is not None:
|
||||
return {"User-Agent": user_agent}
|
||||
|
||||
return {"User-Agent": f"litellm/{version}"}
|
||||
|
||||
# Initialize headers (User-Agent)
|
||||
headers = get_default_headers()
|
||||
|
||||
# https://www.python-httpx.org/advanced/timeouts
|
||||
_DEFAULT_TIMEOUT = httpx.Timeout(timeout=5.0, connect=5.0)
|
||||
|
|
@ -371,13 +383,16 @@ class AsyncHTTPHandler:
|
|||
shared_session=shared_session,
|
||||
)
|
||||
|
||||
# Get default headers (User-Agent, overridable via LITELLM_USER_AGENT)
|
||||
default_headers = get_default_headers()
|
||||
|
||||
return httpx.AsyncClient(
|
||||
transport=transport,
|
||||
event_hooks=event_hooks,
|
||||
timeout=timeout,
|
||||
verify=ssl_config,
|
||||
cert=cert,
|
||||
headers=headers,
|
||||
headers=default_headers,
|
||||
follow_redirects=True,
|
||||
)
|
||||
|
||||
|
|
@ -899,6 +914,9 @@ class HTTPHandler:
|
|||
# /path/to/client.pem
|
||||
cert = os.getenv("SSL_CERTIFICATE", litellm.ssl_certificate)
|
||||
|
||||
# Get default headers (User-Agent, overridable via LITELLM_USER_AGENT)
|
||||
default_headers = get_default_headers() if not disable_default_headers else None
|
||||
|
||||
if client is None:
|
||||
transport = self._create_sync_transport()
|
||||
|
||||
|
|
@ -908,7 +926,7 @@ class HTTPHandler:
|
|||
timeout=timeout,
|
||||
verify=ssl_config,
|
||||
cert=cert,
|
||||
headers=headers if not disable_default_headers else None,
|
||||
headers=default_headers,
|
||||
follow_redirects=True,
|
||||
)
|
||||
else:
|
||||
|
|
|
|||
|
|
@ -1,3 +1,4 @@
|
|||
import os
|
||||
from typing import Optional, Union
|
||||
|
||||
import httpx
|
||||
|
|
@ -7,13 +8,22 @@ try:
|
|||
except Exception:
|
||||
version = "0.0.0"
|
||||
|
||||
headers = {
|
||||
"User-Agent": f"litellm/{version}",
|
||||
}
|
||||
def get_default_headers() -> dict:
|
||||
"""
|
||||
Get default headers for HTTP requests.
|
||||
|
||||
- Default: `User-Agent: litellm/{version}`
|
||||
- Override: set `LITELLM_USER_AGENT` to fully override the header value.
|
||||
"""
|
||||
user_agent = os.environ.get("LITELLM_USER_AGENT")
|
||||
if user_agent is not None:
|
||||
return {"User-Agent": user_agent}
|
||||
|
||||
return {"User-Agent": f"litellm/{version}"}
|
||||
|
||||
class HTTPHandler:
|
||||
def __init__(self, concurrent_limit=1000):
|
||||
headers = get_default_headers()
|
||||
# Create a client with a connection pool
|
||||
self.client = httpx.AsyncClient(
|
||||
limits=httpx.Limits(
|
||||
|
|
|
|||
|
|
@ -4,7 +4,7 @@ Supports writing files to Google AI Studio Files API.
|
|||
For vertex ai, check out the vertex_ai/files/handler.py file.
|
||||
"""
|
||||
import time
|
||||
from typing import List, Optional
|
||||
from typing import Any, List, Literal, Optional
|
||||
|
||||
import httpx
|
||||
from openai.types.file_deleted import FileDeleted
|
||||
|
|
@ -17,6 +17,7 @@ from litellm.llms.base_llm.files.transformation import (
|
|||
)
|
||||
from litellm.types.llms.gemini import GeminiCreateFilesResponseObject
|
||||
from litellm.types.llms.openai import (
|
||||
AllMessageValues,
|
||||
CreateFileRequest,
|
||||
HttpxBinaryResponseContent,
|
||||
OpenAICreateFileRequestOptionalParams,
|
||||
|
|
@ -37,22 +38,23 @@ class GoogleAIStudioFilesHandler(GeminiModelInfo, BaseFilesConfig):
|
|||
|
||||
def validate_environment(
|
||||
self,
|
||||
api_key: Optional[str],
|
||||
headers: dict,
|
||||
headers: dict[Any, Any],
|
||||
model: str,
|
||||
messages: list,
|
||||
optional_params: dict,
|
||||
litellm_params: dict,
|
||||
) -> dict:
|
||||
messages: List[AllMessageValues],
|
||||
optional_params: dict[Any, Any],
|
||||
litellm_params: dict[Any, Any],
|
||||
api_key: Optional[str] = None,
|
||||
api_base: Optional[str] = None,
|
||||
) -> dict[Any, Any]:
|
||||
"""
|
||||
Validate environment and add Gemini API key to headers.
|
||||
Google AI Studio uses x-goog-api-key header for authentication.
|
||||
"""
|
||||
api_key = self.get_api_key(api_key)
|
||||
if not api_key:
|
||||
resolved_api_key = self.get_api_key(api_key)
|
||||
if not resolved_api_key:
|
||||
raise ValueError("GEMINI_API_KEY is required for Google AI Studio file operations")
|
||||
|
||||
headers["x-goog-api-key"] = api_key
|
||||
headers["x-goog-api-key"] = resolved_api_key
|
||||
return headers
|
||||
|
||||
def get_complete_url(
|
||||
|
|
@ -236,11 +238,13 @@ class GoogleAIStudioFilesHandler(GeminiModelInfo, BaseFilesConfig):
|
|||
|
||||
# Map Gemini state to OpenAI status
|
||||
gemini_state = response_json.get("state", "STATE_UNSPECIFIED")
|
||||
status = "uploaded" # Default
|
||||
# Explicitly type status as the Literal union
|
||||
if gemini_state == "ACTIVE":
|
||||
status = "processed"
|
||||
status: Literal["uploaded", "processed", "error"] = "processed"
|
||||
elif gemini_state == "FAILED":
|
||||
status = "error"
|
||||
else:
|
||||
status = "uploaded"
|
||||
|
||||
return OpenAIFileObject(
|
||||
id=response_json.get("uri", ""),
|
||||
|
|
@ -301,7 +305,7 @@ class GoogleAIStudioFilesHandler(GeminiModelInfo, BaseFilesConfig):
|
|||
url = f"{api_base}/v1beta/{file_name}"
|
||||
|
||||
# Add API key as header (Google AI Studio uses x-goog-api-key header)
|
||||
params = {}
|
||||
params: dict = {}
|
||||
|
||||
return url, params
|
||||
|
||||
|
|
|
|||
|
|
@ -255,9 +255,11 @@ class GoogleImageGenConfig(BaseImageGenerationConfig):
|
|||
if "inlineData" in part:
|
||||
inline_data = part["inlineData"]
|
||||
if "data" in inline_data:
|
||||
thought_sig = part.get("thoughtSignature")
|
||||
model_response.data.append(ImageObject(
|
||||
b64_json=inline_data["data"],
|
||||
url=None,
|
||||
provider_specific_fields={"thought_signature": thought_sig} if thought_sig else None,
|
||||
))
|
||||
|
||||
# Extract usage metadata for Gemini models
|
||||
|
|
|
|||
|
|
@ -27,6 +27,8 @@ local_cache_obj = Cache(
|
|||
type=LiteLLMCacheType.LOCAL
|
||||
) # only used for calling 'get_cache_key' function
|
||||
|
||||
MAX_PAGINATION_PAGES = 100 # Reasonable upper bound for pagination
|
||||
|
||||
|
||||
class ContextCachingEndpoints(VertexBase):
|
||||
"""
|
||||
|
|
@ -115,7 +117,7 @@ class ContextCachingEndpoints(VertexBase):
|
|||
- None
|
||||
"""
|
||||
|
||||
_, url = self._get_token_and_url_context_caching(
|
||||
_, base_url = self._get_token_and_url_context_caching(
|
||||
gemini_api_key=api_key,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
api_base=api_base,
|
||||
|
|
@ -123,43 +125,63 @@ class ContextCachingEndpoints(VertexBase):
|
|||
vertex_location=vertex_location,
|
||||
vertex_auth_header=vertex_auth_header
|
||||
)
|
||||
try:
|
||||
## LOGGING
|
||||
logging_obj.pre_call(
|
||||
input="",
|
||||
api_key="",
|
||||
additional_args={
|
||||
"complete_input_dict": {},
|
||||
"api_base": url,
|
||||
"headers": headers,
|
||||
},
|
||||
)
|
||||
|
||||
resp = client.get(url=url, headers=headers)
|
||||
resp.raise_for_status()
|
||||
except httpx.HTTPStatusError as e:
|
||||
if e.response.status_code == 403:
|
||||
page_token: Optional[str] = None
|
||||
|
||||
# Iterate through all pages
|
||||
for _ in range(MAX_PAGINATION_PAGES):
|
||||
# Build URL with pagination token if present
|
||||
if page_token:
|
||||
separator = "&" if "?" in base_url else "?"
|
||||
url = f"{base_url}{separator}pageToken={page_token}"
|
||||
else:
|
||||
url = base_url
|
||||
|
||||
try:
|
||||
## LOGGING
|
||||
logging_obj.pre_call(
|
||||
input="",
|
||||
api_key="",
|
||||
additional_args={
|
||||
"complete_input_dict": {},
|
||||
"api_base": url,
|
||||
"headers": headers,
|
||||
},
|
||||
)
|
||||
|
||||
resp = client.get(url=url, headers=headers)
|
||||
resp.raise_for_status()
|
||||
except httpx.HTTPStatusError as e:
|
||||
if e.response.status_code == 403:
|
||||
return None
|
||||
raise VertexAIError(
|
||||
status_code=e.response.status_code, message=e.response.text
|
||||
)
|
||||
except Exception as e:
|
||||
raise VertexAIError(status_code=500, message=str(e))
|
||||
|
||||
raw_response = resp.json()
|
||||
logging_obj.post_call(original_response=raw_response)
|
||||
|
||||
if "cachedContents" not in raw_response:
|
||||
return None
|
||||
raise VertexAIError(
|
||||
status_code=e.response.status_code, message=e.response.text
|
||||
)
|
||||
except Exception as e:
|
||||
raise VertexAIError(status_code=500, message=str(e))
|
||||
raw_response = resp.json()
|
||||
logging_obj.post_call(original_response=raw_response)
|
||||
|
||||
if "cachedContents" not in raw_response:
|
||||
return None
|
||||
all_cached_items = CachedContentListAllResponseBody(**raw_response)
|
||||
|
||||
all_cached_items = CachedContentListAllResponseBody(**raw_response)
|
||||
if "cachedContents" not in all_cached_items:
|
||||
return None
|
||||
|
||||
if "cachedContents" not in all_cached_items:
|
||||
return None
|
||||
# Check current page for matching cache_key
|
||||
for cached_item in all_cached_items["cachedContents"]:
|
||||
display_name = cached_item.get("displayName")
|
||||
if display_name is not None and display_name == cache_key:
|
||||
return cached_item.get("name")
|
||||
|
||||
for cached_item in all_cached_items["cachedContents"]:
|
||||
display_name = cached_item.get("displayName")
|
||||
if display_name is not None and display_name == cache_key:
|
||||
return cached_item.get("name")
|
||||
# Check if there are more pages
|
||||
page_token = all_cached_items.get("nextPageToken")
|
||||
if not page_token:
|
||||
# No more pages, cache not found
|
||||
break
|
||||
|
||||
return None
|
||||
|
||||
|
|
@ -187,7 +209,7 @@ class ContextCachingEndpoints(VertexBase):
|
|||
- None
|
||||
"""
|
||||
|
||||
_, url = self._get_token_and_url_context_caching(
|
||||
_, base_url = self._get_token_and_url_context_caching(
|
||||
gemini_api_key=api_key,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
api_base=api_base,
|
||||
|
|
@ -195,43 +217,63 @@ class ContextCachingEndpoints(VertexBase):
|
|||
vertex_location=vertex_location,
|
||||
vertex_auth_header=vertex_auth_header
|
||||
)
|
||||
try:
|
||||
## LOGGING
|
||||
logging_obj.pre_call(
|
||||
input="",
|
||||
api_key="",
|
||||
additional_args={
|
||||
"complete_input_dict": {},
|
||||
"api_base": url,
|
||||
"headers": headers,
|
||||
},
|
||||
)
|
||||
|
||||
resp = await client.get(url=url, headers=headers)
|
||||
resp.raise_for_status()
|
||||
except httpx.HTTPStatusError as e:
|
||||
if e.response.status_code == 403:
|
||||
page_token: Optional[str] = None
|
||||
|
||||
# Iterate through all pages
|
||||
for _ in range(MAX_PAGINATION_PAGES):
|
||||
# Build URL with pagination token if present
|
||||
if page_token:
|
||||
separator = "&" if "?" in base_url else "?"
|
||||
url = f"{base_url}{separator}pageToken={page_token}"
|
||||
else:
|
||||
url = base_url
|
||||
|
||||
try:
|
||||
## LOGGING
|
||||
logging_obj.pre_call(
|
||||
input="",
|
||||
api_key="",
|
||||
additional_args={
|
||||
"complete_input_dict": {},
|
||||
"api_base": url,
|
||||
"headers": headers,
|
||||
},
|
||||
)
|
||||
|
||||
resp = await client.get(url=url, headers=headers)
|
||||
resp.raise_for_status()
|
||||
except httpx.HTTPStatusError as e:
|
||||
if e.response.status_code == 403:
|
||||
return None
|
||||
raise VertexAIError(
|
||||
status_code=e.response.status_code, message=e.response.text
|
||||
)
|
||||
except Exception as e:
|
||||
raise VertexAIError(status_code=500, message=str(e))
|
||||
|
||||
raw_response = resp.json()
|
||||
logging_obj.post_call(original_response=raw_response)
|
||||
|
||||
if "cachedContents" not in raw_response:
|
||||
return None
|
||||
raise VertexAIError(
|
||||
status_code=e.response.status_code, message=e.response.text
|
||||
)
|
||||
except Exception as e:
|
||||
raise VertexAIError(status_code=500, message=str(e))
|
||||
raw_response = resp.json()
|
||||
logging_obj.post_call(original_response=raw_response)
|
||||
|
||||
if "cachedContents" not in raw_response:
|
||||
return None
|
||||
all_cached_items = CachedContentListAllResponseBody(**raw_response)
|
||||
|
||||
all_cached_items = CachedContentListAllResponseBody(**raw_response)
|
||||
if "cachedContents" not in all_cached_items:
|
||||
return None
|
||||
|
||||
if "cachedContents" not in all_cached_items:
|
||||
return None
|
||||
# Check current page for matching cache_key
|
||||
for cached_item in all_cached_items["cachedContents"]:
|
||||
display_name = cached_item.get("displayName")
|
||||
if display_name is not None and display_name == cache_key:
|
||||
return cached_item.get("name")
|
||||
|
||||
for cached_item in all_cached_items["cachedContents"]:
|
||||
display_name = cached_item.get("displayName")
|
||||
if display_name is not None and display_name == cache_key:
|
||||
return cached_item.get("name")
|
||||
# Check if there are more pages
|
||||
page_token = all_cached_items.get("nextPageToken")
|
||||
if not page_token:
|
||||
# No more pages, cache not found
|
||||
break
|
||||
|
||||
return None
|
||||
|
||||
|
|
@ -501,4 +543,4 @@ class ContextCachingEndpoints(VertexBase):
|
|||
pass
|
||||
|
||||
async def async_get_cache(self):
|
||||
pass
|
||||
pass
|
||||
|
|
@ -295,9 +295,11 @@ class VertexAIGeminiImageGenerationConfig(BaseImageGenerationConfig, VertexLLM):
|
|||
if "inlineData" in part:
|
||||
inline_data = part["inlineData"]
|
||||
if "data" in inline_data:
|
||||
thought_sig = part.get("thoughtSignature")
|
||||
model_response.data.append(ImageObject(
|
||||
b64_json=inline_data["data"],
|
||||
url=None,
|
||||
provider_specific_fields={"thought_signature": thought_sig} if thought_sig else None,
|
||||
))
|
||||
|
||||
if usage_metadata := response_data.get("usageMetadata", None):
|
||||
|
|
|
|||
|
|
@ -20,6 +20,7 @@ from .common_utils import (
|
|||
_get_vertex_url,
|
||||
all_gemini_url_modes,
|
||||
get_vertex_base_model_name,
|
||||
get_vertex_base_url,
|
||||
is_global_only_vertex_model,
|
||||
)
|
||||
|
||||
|
|
@ -200,12 +201,7 @@ class VertexBase:
|
|||
) -> str:
|
||||
if api_base:
|
||||
return api_base
|
||||
elif vertex_location == "global":
|
||||
return "https://aiplatform.googleapis.com"
|
||||
elif vertex_location:
|
||||
return f"https://{vertex_location}-aiplatform.googleapis.com"
|
||||
else:
|
||||
return f"https://{self.get_default_vertex_location()}-aiplatform.googleapis.com"
|
||||
return get_vertex_base_url(vertex_location or self.get_default_vertex_location())
|
||||
|
||||
@staticmethod
|
||||
def create_vertex_url(
|
||||
|
|
@ -218,7 +214,8 @@ class VertexBase:
|
|||
) -> str:
|
||||
"""Return the base url for the vertex partner models"""
|
||||
|
||||
api_base = api_base or f"https://{vertex_location}-aiplatform.googleapis.com"
|
||||
if api_base is None:
|
||||
api_base = get_vertex_base_url(vertex_location)
|
||||
if partner == VertexPartnerProvider.llama:
|
||||
return f"{api_base}/v1/projects/{vertex_project}/locations/{vertex_location}/endpoints/openapi/chat/completions"
|
||||
elif partner == VertexPartnerProvider.mistralai:
|
||||
|
|
@ -247,11 +244,13 @@ class VertexBase:
|
|||
stream: Optional[bool],
|
||||
model: str,
|
||||
) -> str:
|
||||
# Use get_vertex_region to handle global-only models
|
||||
resolved_location = self.get_vertex_region(vertex_location, model)
|
||||
api_base = self.get_api_base(
|
||||
api_base=custom_api_base, vertex_location=vertex_location
|
||||
api_base=custom_api_base, vertex_location=resolved_location
|
||||
)
|
||||
default_api_base = VertexBase.create_vertex_url(
|
||||
vertex_location=vertex_location or "us-central1",
|
||||
vertex_location=resolved_location,
|
||||
vertex_project=vertex_project or project_id,
|
||||
partner=partner,
|
||||
stream=stream,
|
||||
|
|
@ -274,7 +273,7 @@ class VertexBase:
|
|||
url=default_api_base,
|
||||
model=model,
|
||||
vertex_project=vertex_project or project_id,
|
||||
vertex_location=vertex_location or "us-central1",
|
||||
vertex_location=resolved_location,
|
||||
vertex_api_version="v1", # Partner models typically use v1
|
||||
)
|
||||
return api_base
|
||||
|
|
|
|||
|
|
@ -42,6 +42,7 @@ def generate_iam_token(api_key=None, **params) -> str:
|
|||
get_secret_str("WX_API_KEY")
|
||||
or get_secret_str("WATSONX_API_KEY")
|
||||
or get_secret_str("WATSONX_APIKEY")
|
||||
or get_secret_str("WATSONX_ZENAPIKEY")
|
||||
)
|
||||
if api_key is None:
|
||||
raise ValueError("API key is required")
|
||||
|
|
@ -319,6 +320,7 @@ class IBMWatsonXMixin:
|
|||
or get_secret_str("WATSONX_APIKEY")
|
||||
or get_secret_str("WATSONX_API_KEY")
|
||||
or get_secret_str("WX_API_KEY")
|
||||
or get_secret_str("WATSONX_ZENAPIKEY")
|
||||
)
|
||||
|
||||
api_base = (
|
||||
|
|
|
|||
|
|
@ -4709,11 +4709,11 @@ def embedding( # noqa: PLR0915
|
|||
litellm_params=litellm_params_dict,
|
||||
)
|
||||
elif (
|
||||
model in litellm.open_ai_embedding_models
|
||||
or custom_llm_provider == "openai"
|
||||
custom_llm_provider == "openai"
|
||||
or custom_llm_provider == "together_ai"
|
||||
or custom_llm_provider == "nvidia_nim"
|
||||
or custom_llm_provider == "litellm_proxy"
|
||||
or (model in litellm.open_ai_embedding_models and custom_llm_provider is None)
|
||||
):
|
||||
api_base = (
|
||||
api_base
|
||||
|
|
|
|||
|
|
@ -749,7 +749,7 @@
|
|||
"anthropic.claude-3-5-sonnet-20240620-v1:0": {
|
||||
"input_cost_per_token": 3e-06,
|
||||
"litellm_provider": "bedrock",
|
||||
"max_input_tokens": 200000,
|
||||
"max_input_tokens": 1000000,
|
||||
"max_output_tokens": 4096,
|
||||
"max_tokens": 4096,
|
||||
"mode": "chat",
|
||||
|
|
@ -758,14 +758,22 @@
|
|||
"supports_pdf_input": true,
|
||||
"supports_response_schema": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_vision": true
|
||||
"supports_vision": true,
|
||||
"input_cost_per_token_above_200k_tokens": 6e-06,
|
||||
"output_cost_per_token_above_200k_tokens": 3e-05,
|
||||
"cache_creation_input_token_cost_above_200k_tokens": 7.5e-06,
|
||||
"cache_read_input_token_cost_above_200k_tokens": 6e-07,
|
||||
"cache_creation_input_token_cost_above_1hr": 7.5e-06,
|
||||
"cache_creation_input_token_cost_above_1hr_above_200k_tokens": 1.5e-05,
|
||||
"cache_creation_input_token_cost": 3.75e-06,
|
||||
"cache_read_input_token_cost": 3e-07
|
||||
},
|
||||
"anthropic.claude-3-5-sonnet-20241022-v2:0": {
|
||||
"cache_creation_input_token_cost": 3.75e-06,
|
||||
"cache_read_input_token_cost": 3e-07,
|
||||
"input_cost_per_token": 3e-06,
|
||||
"litellm_provider": "bedrock",
|
||||
"max_input_tokens": 200000,
|
||||
"max_input_tokens": 1000000,
|
||||
"max_output_tokens": 8192,
|
||||
"max_tokens": 8192,
|
||||
"mode": "chat",
|
||||
|
|
@ -777,7 +785,13 @@
|
|||
"supports_prompt_caching": true,
|
||||
"supports_response_schema": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_vision": true
|
||||
"supports_vision": true,
|
||||
"input_cost_per_token_above_200k_tokens": 6e-06,
|
||||
"output_cost_per_token_above_200k_tokens": 3e-05,
|
||||
"cache_creation_input_token_cost_above_200k_tokens": 7.5e-06,
|
||||
"cache_read_input_token_cost_above_200k_tokens": 6e-07,
|
||||
"cache_creation_input_token_cost_above_1hr": 7.5e-06,
|
||||
"cache_creation_input_token_cost_above_1hr_above_200k_tokens": 1.5e-05
|
||||
},
|
||||
"anthropic.claude-3-7-sonnet-20240620-v1:0": {
|
||||
"cache_creation_input_token_cost": 4.5e-06,
|
||||
|
|
@ -6715,13 +6729,13 @@
|
|||
"supports_tool_choice": true
|
||||
},
|
||||
"cerebras/gpt-oss-120b": {
|
||||
"input_cost_per_token": 2.5e-07,
|
||||
"input_cost_per_token": 3.5e-07,
|
||||
"litellm_provider": "cerebras",
|
||||
"max_input_tokens": 131072,
|
||||
"max_output_tokens": 32768,
|
||||
"max_tokens": 32768,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 6.9e-07,
|
||||
"output_cost_per_token": 7.5e-07,
|
||||
"source": "https://www.cerebras.ai/blog/openai-gpt-oss-120b-runs-fastest-on-cerebras",
|
||||
"supports_function_calling": true,
|
||||
"supports_parallel_function_calling": true,
|
||||
|
|
@ -6739,6 +6753,7 @@
|
|||
"output_cost_per_token": 8e-07,
|
||||
"source": "https://inference-docs.cerebras.ai/support/pricing",
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
"cerebras/zai-glm-4.6": {
|
||||
|
|
@ -24390,21 +24405,21 @@
|
|||
"supports_tool_choice": true
|
||||
},
|
||||
"openrouter/xiaomi/mimo-v2-flash": {
|
||||
"input_cost_per_token": 9e-08,
|
||||
"output_cost_per_token": 2.9e-07,
|
||||
"cache_creation_input_token_cost": 0.0,
|
||||
"cache_read_input_token_cost": 0.0,
|
||||
"litellm_provider": "openrouter",
|
||||
"max_input_tokens": 262144,
|
||||
"max_output_tokens": 16384,
|
||||
"max_tokens": 16384,
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_vision": false,
|
||||
"supports_prompt_caching": false
|
||||
},
|
||||
"openrouter/z-ai/glm-4.7": {
|
||||
"input_cost_per_token": 4e-07,
|
||||
"output_cost_per_token": 1.5e-06,
|
||||
|
|
@ -26319,13 +26334,13 @@
|
|||
"litellm_provider": "bedrock",
|
||||
"max_input_tokens": 77,
|
||||
"mode": "image_edit",
|
||||
"output_cost_per_image": 0.40
|
||||
"output_cost_per_image": 0.4
|
||||
},
|
||||
"stability.stable-creative-upscale-v1:0": {
|
||||
"litellm_provider": "bedrock",
|
||||
"max_input_tokens": 77,
|
||||
"mode": "image_edit",
|
||||
"output_cost_per_image": 0.60
|
||||
"output_cost_per_image": 0.6
|
||||
},
|
||||
"stability.stable-fast-upscale-v1:0": {
|
||||
"litellm_provider": "bedrock",
|
||||
|
|
@ -29770,6 +29785,7 @@
|
|||
"mode": "chat",
|
||||
"output_cost_per_token": 1e-06,
|
||||
"source": "https://cloud.google.com/vertex-ai/generative-ai/pricing",
|
||||
"supported_regions": ["global"],
|
||||
"supports_function_calling": true,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
|
|
@ -29782,6 +29798,7 @@
|
|||
"mode": "chat",
|
||||
"output_cost_per_token": 4e-06,
|
||||
"source": "https://cloud.google.com/vertex-ai/generative-ai/pricing",
|
||||
"supported_regions": ["global"],
|
||||
"supports_function_calling": true,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
|
|
@ -29794,6 +29811,7 @@
|
|||
"mode": "chat",
|
||||
"output_cost_per_token": 1.2e-06,
|
||||
"source": "https://cloud.google.com/vertex-ai/generative-ai/pricing",
|
||||
"supported_regions": ["global"],
|
||||
"supports_function_calling": true,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
|
|
@ -29806,6 +29824,7 @@
|
|||
"mode": "chat",
|
||||
"output_cost_per_token": 1.2e-06,
|
||||
"source": "https://cloud.google.com/vertex-ai/generative-ai/pricing",
|
||||
"supported_regions": ["global"],
|
||||
"supports_function_calling": true,
|
||||
"supports_tool_choice": true
|
||||
},
|
||||
|
|
|
|||
|
|
@ -11,7 +11,7 @@ import datetime
|
|||
import hashlib
|
||||
import json
|
||||
import re
|
||||
from typing import Any, Dict, List, Literal, Optional, Set, Tuple, Union, cast, Callable
|
||||
from typing import Any, Callable, Dict, List, Literal, Optional, Set, Tuple, Union, cast
|
||||
from urllib.parse import urlparse
|
||||
|
||||
from fastapi import HTTPException
|
||||
|
|
@ -30,7 +30,6 @@ from pydantic import AnyUrl
|
|||
|
||||
import litellm
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.types.utils import CallTypes
|
||||
from litellm.exceptions import BlockedPiiEntityError, GuardrailRaisedException
|
||||
from litellm.experimental_mcp_client.client import MCPClient
|
||||
from litellm.llms.custom_httpx.http_handler import get_async_httpx_client
|
||||
|
|
@ -63,20 +62,23 @@ from litellm.types.mcp_server.mcp_server_manager import (
|
|||
MCPOAuthMetadata,
|
||||
MCPServer,
|
||||
)
|
||||
from litellm.types.utils import CallTypes
|
||||
|
||||
try:
|
||||
from mcp.shared.tool_name_validation import SEP_986_URL, validate_tool_name # type: ignore
|
||||
from mcp.shared.tool_name_validation import ( # type: ignore
|
||||
SEP_986_URL,
|
||||
validate_tool_name,
|
||||
)
|
||||
except ImportError:
|
||||
from pydantic import BaseModel
|
||||
SEP_986_URL = "https://github.com/modelcontextprotocol/protocol/blob/main/proposals/0001-tool-name-validation.md"
|
||||
|
||||
def validate_tool_name(name: str):
|
||||
from pydantic import BaseModel
|
||||
class ToolNameValidationResult(BaseModel):
|
||||
is_valid: bool = True
|
||||
warnings: list = []
|
||||
|
||||
class MockResult(BaseModel):
|
||||
is_valid: bool = True
|
||||
warnings: list = []
|
||||
|
||||
return MockResult()
|
||||
def validate_tool_name(name: str) -> ToolNameValidationResult: # type: ignore[misc]
|
||||
return ToolNameValidationResult()
|
||||
|
||||
|
||||
# Probe includes characters on both sides of the separator to mimic real prefixed tool names.
|
||||
|
|
|
|||
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue