mirror of
https://github.com/BerriAI/litellm.git
synced 2026-09-22 00:31:44 +00:00
Merge branch 'main' into litellm_specific_oom_issue
This commit is contained in:
 Alexsander Hamir
commit
185495dbdb
418 changed files with 16046 additions and 2788 deletions
8
.github/ISSUE_TEMPLATE/bug_report.yml
vendored
8
.github/ISSUE_TEMPLATE/bug_report.yml
vendored
|
|
@ -9,6 +9,14 @@ body:
|
|||
Thanks for taking the time to fill out this bug report!
|
||||
|
||||
**💡 Tip:** See our [Troubleshooting Guide](https://docs.litellm.ai/docs/troubleshoot) for what information to include.
|
||||
- type: checkboxes
|
||||
id: duplicate-check
|
||||
attributes:
|
||||
label: Check for existing issues
|
||||
description: Please search to see if an issue already exists for the bug you encountered.
|
||||
options:
|
||||
- label: I have searched the existing issues and checked that my issue is not a duplicate.
|
||||
required: true
|
||||
- type: textarea
|
||||
id: what-happened
|
||||
attributes:
|
||||
|
|
|
|||
8
.github/ISSUE_TEMPLATE/feature_request.yml
vendored
8
.github/ISSUE_TEMPLATE/feature_request.yml
vendored
|
|
@ -7,6 +7,14 @@ body:
|
|||
attributes:
|
||||
value: |
|
||||
Thanks for making LiteLLM better!
|
||||
- type: checkboxes
|
||||
id: duplicate-check
|
||||
attributes:
|
||||
label: Check for existing issues
|
||||
description: Please search to see if an issue already exists for the feature you are requesting.
|
||||
options:
|
||||
- label: I have searched the existing issues and checked that my issue is not a duplicate.
|
||||
required: true
|
||||
- type: textarea
|
||||
id: the-feature
|
||||
attributes:
|
||||
|
|
|
|||
29
.github/workflows/check_duplicate_issues.yml
vendored
Normal file
29
.github/workflows/check_duplicate_issues.yml
vendored
Normal file
|
|
@ -0,0 +1,29 @@
|
|||
name: Check Duplicate Issues
|
||||
|
||||
on:
|
||||
issues:
|
||||
types: [opened, edited]
|
||||
|
||||
jobs:
|
||||
check-duplicate:
|
||||
runs-on: ubuntu-latest
|
||||
permissions:
|
||||
issues: write
|
||||
contents: read
|
||||
steps:
|
||||
- name: Check for potential duplicates
|
||||
uses: wow-actions/potential-duplicates@v1
|
||||
with:
|
||||
GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
|
||||
label: potential-duplicate
|
||||
threshold: 0.6
|
||||
reaction: eyes
|
||||
comment: |
|
||||
**⚠️ Potential duplicate detected**
|
||||
|
||||
This issue appears similar to existing issue(s):
|
||||
{{#issues}}
|
||||
- [#{{number}}]({{html_url}}) - {{title}} ({{accuracy}}% similar)
|
||||
{{/issues}}
|
||||
|
||||
Please review the linked issue(s) to see if they address your concern. If this is not a duplicate, please provide additional context to help us understand the difference.
|
||||
34
.github/workflows/label-component.yml
vendored
34
.github/workflows/label-component.yml
vendored
|
|
@ -80,3 +80,37 @@ jobs:
|
|||
break;
|
||||
}
|
||||
}
|
||||
|
||||
// Check for 'claude code' keyword (can be applied alongside component labels)
|
||||
if (/claude code/i.test(body)) {
|
||||
const claudeLabel = {
|
||||
name: 'claude code',
|
||||
color: '7c3aed',
|
||||
description: 'Issues related to Claude Code usage'
|
||||
};
|
||||
|
||||
try {
|
||||
await github.rest.issues.getLabel({
|
||||
owner: context.repo.owner,
|
||||
repo: context.repo.repo,
|
||||
name: claudeLabel.name
|
||||
});
|
||||
} catch (error) {
|
||||
if (error.status === 404) {
|
||||
await github.rest.issues.createLabel({
|
||||
owner: context.repo.owner,
|
||||
repo: context.repo.repo,
|
||||
name: claudeLabel.name,
|
||||
color: claudeLabel.color,
|
||||
description: claudeLabel.description
|
||||
});
|
||||
}
|
||||
}
|
||||
|
||||
await github.rest.issues.addLabels({
|
||||
owner: context.repo.owner,
|
||||
repo: context.repo.repo,
|
||||
issue_number: context.issue.number,
|
||||
labels: [claudeLabel.name]
|
||||
});
|
||||
}
|
||||
|
|
|
|||
127
ARCHITECTURE.md
127
ARCHITECTURE.md
|
|
@ -28,16 +28,25 @@ sequenceDiagram
|
|||
participant Client
|
||||
participant ProxyServer as proxy/proxy_server.py
|
||||
participant Auth as proxy/auth/user_api_key_auth.py
|
||||
participant Redis as Redis Cache
|
||||
participant Hooks as proxy/hooks/
|
||||
participant Router as router.py
|
||||
participant Main as main.py
|
||||
participant Main as main.py + utils.py
|
||||
participant Handler as llms/custom_httpx/llm_http_handler.py
|
||||
participant Transform as llms/{provider}/chat/transformation.py
|
||||
participant Provider as LLM Provider API
|
||||
participant CostCalc as cost_calculator.py
|
||||
participant LoggingObj as litellm_logging.py
|
||||
participant DBWriter as db/db_spend_update_writer.py
|
||||
participant Postgres as PostgreSQL
|
||||
|
||||
%% Request Flow
|
||||
Client->>ProxyServer: POST /v1/chat/completions
|
||||
ProxyServer->>Auth: user_api_key_auth()
|
||||
Auth->>Redis: Check API key cache
|
||||
Redis-->>Auth: Key info + spend limits
|
||||
ProxyServer->>Hooks: max_budget_limiter, parallel_request_limiter
|
||||
Hooks->>Redis: Check/increment rate limit counters
|
||||
ProxyServer->>Router: route_request()
|
||||
Router->>Main: litellm.acompletion()
|
||||
Main->>Handler: BaseLLMHTTPHandler.completion()
|
||||
|
|
@ -45,8 +54,25 @@ sequenceDiagram
|
|||
Handler->>Provider: HTTP Request
|
||||
Provider-->>Handler: Response
|
||||
Handler->>Transform: ProviderConfig.transform_response()
|
||||
Handler-->>Hooks: async_log_success_event()
|
||||
Handler-->>Client: ModelResponse
|
||||
Transform-->>Handler: ModelResponse
|
||||
Handler-->>Main: ModelResponse
|
||||
|
||||
%% Cost Attribution (in utils.py wrapper)
|
||||
Main->>LoggingObj: update_response_metadata()
|
||||
LoggingObj->>CostCalc: _response_cost_calculator()
|
||||
CostCalc->>CostCalc: completion_cost(tokens × price)
|
||||
CostCalc-->>LoggingObj: response_cost
|
||||
LoggingObj-->>Main: Set response._hidden_params["response_cost"]
|
||||
Main-->>ProxyServer: ModelResponse (with cost in _hidden_params)
|
||||
|
||||
%% Response Headers + Async Logging
|
||||
ProxyServer->>ProxyServer: Extract cost from hidden_params
|
||||
ProxyServer->>LoggingObj: async_success_handler()
|
||||
LoggingObj->>Hooks: async_log_success_event()
|
||||
Hooks->>DBWriter: update_database(response_cost)
|
||||
DBWriter->>Redis: Queue spend increment
|
||||
DBWriter->>Postgres: Batch write spend logs (async)
|
||||
ProxyServer-->>Client: ModelResponse + x-litellm-response-cost header
|
||||
```
|
||||
|
||||
### Proxy Components
|
||||
|
|
@ -75,11 +101,19 @@ graph TD
|
|||
Main["main.py"]
|
||||
end
|
||||
|
||||
subgraph "Infrastructure"
|
||||
DualCache["DualCache<br/>(in-memory + Redis)"]
|
||||
Postgres["PostgreSQL<br/>(keys, teams, spend logs)"]
|
||||
end
|
||||
|
||||
Client --> Endpoint
|
||||
Endpoint --> Auth
|
||||
Auth --> DualCache
|
||||
DualCache -.->|cache miss| Postgres
|
||||
Auth --> PreCall
|
||||
PreCall --> RouteRequest
|
||||
RouteRequest --> Router
|
||||
Router --> DualCache
|
||||
Router --> Main
|
||||
Main --> Client
|
||||
```
|
||||
|
|
@ -119,6 +153,93 @@ graph TD
|
|||
|
||||
To add a new proxy hook, implement `CustomLogger` and register in `PROXY_HOOKS`.
|
||||
|
||||
### Infrastructure Components
|
||||
|
||||
The AI Gateway uses external infrastructure for persistence and caching:
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
subgraph "AI Gateway (proxy/)"
|
||||
Proxy["proxy_server.py"]
|
||||
Auth["auth/user_api_key_auth.py"]
|
||||
DBWriter["db/db_spend_update_writer.py<br/>DBSpendUpdateWriter"]
|
||||
InternalCache["utils.py<br/>InternalUsageCache"]
|
||||
CostCallback["hooks/proxy_track_cost_callback.py<br/>_ProxyDBLogger"]
|
||||
Scheduler["APScheduler<br/>ProxyStartupEvent"]
|
||||
end
|
||||
|
||||
subgraph "SDK (litellm/)"
|
||||
Router["router.py<br/>Router.cache (DualCache)"]
|
||||
LLMCache["caching/caching_handler.py<br/>LLMCachingHandler"]
|
||||
CacheClass["caching/caching.py<br/>Cache"]
|
||||
end
|
||||
|
||||
subgraph "Redis (caching/redis_cache.py)"
|
||||
RateLimit["Rate Limit Counters"]
|
||||
SpendQueue["Spend Increment Queue"]
|
||||
KeyCache["API Key Cache"]
|
||||
TPM_RPM["TPM/RPM Tracking"]
|
||||
Cooldowns["Deployment Cooldowns"]
|
||||
LLMResponseCache["LLM Response Cache"]
|
||||
end
|
||||
|
||||
subgraph "PostgreSQL (proxy/schema.prisma)"
|
||||
Keys["LiteLLM_VerificationToken"]
|
||||
Teams["LiteLLM_TeamTable"]
|
||||
SpendLogs["LiteLLM_SpendLogs"]
|
||||
Users["LiteLLM_UserTable"]
|
||||
end
|
||||
|
||||
Auth --> InternalCache
|
||||
InternalCache --> KeyCache
|
||||
InternalCache -.->|cache miss| Keys
|
||||
InternalCache --> RateLimit
|
||||
Router --> TPM_RPM
|
||||
Router --> Cooldowns
|
||||
LLMCache --> CacheClass
|
||||
CacheClass --> LLMResponseCache
|
||||
CostCallback --> DBWriter
|
||||
DBWriter --> SpendQueue
|
||||
DBWriter --> SpendLogs
|
||||
Scheduler --> SpendLogs
|
||||
Scheduler --> Keys
|
||||
```
|
||||
|
||||
| Component | Purpose | Key Files/Classes |
|
||||
|-----------|---------|-------------------|
|
||||
| **Redis** | Rate limiting, API key caching, TPM/RPM tracking, cooldowns, LLM response caching, spend queuing | `caching/redis_cache.py` (`RedisCache`), `caching/dual_cache.py` (`DualCache`) |
|
||||
| **PostgreSQL** | API keys, teams, users, spend logs | `proxy/utils.py` (`PrismaClient`), `proxy/schema.prisma` |
|
||||
| **InternalUsageCache** | Proxy-level cache for rate limits + API keys (in-memory + Redis) | `proxy/utils.py` (`InternalUsageCache`) |
|
||||
| **Router.cache** | TPM/RPM tracking, deployment cooldowns, client caching (in-memory + Redis) | `router.py` (`Router.cache: DualCache`) |
|
||||
| **LLMCachingHandler** | SDK-level LLM response/embedding caching | `caching/caching_handler.py` (`LLMCachingHandler`), `caching/caching.py` (`Cache`) |
|
||||
| **DBSpendUpdateWriter** | Batches spend updates to reduce DB writes | `proxy/db/db_spend_update_writer.py` (`DBSpendUpdateWriter`) |
|
||||
| **Cost Tracking** | Calculates and logs response costs | `proxy/hooks/proxy_track_cost_callback.py` (`_ProxyDBLogger`) |
|
||||
|
||||
**Background Jobs** (APScheduler, initialized in `proxy/proxy_server.py` → `ProxyStartupEvent.initialize_scheduled_background_jobs()`):
|
||||
|
||||
| Job | Interval | Purpose | Key Files |
|
||||
|-----|----------|---------|-----------|
|
||||
| `update_spend` | 60s | Batch write spend logs to PostgreSQL | `proxy/db/db_spend_update_writer.py` |
|
||||
| `reset_budget` | 10-12min | Reset budgets for keys/users/teams | `proxy/management_helpers/budget_reset_job.py` |
|
||||
| `add_deployment` | 10s | Sync new model deployments from DB | `proxy/proxy_server.py` (`ProxyConfig`) |
|
||||
| `cleanup_old_spend_logs` | cron/interval | Delete old spend logs | `proxy/management_helpers/spend_log_cleanup.py` |
|
||||
| `check_batch_cost` | 30min | Calculate costs for batch jobs | `proxy/management_helpers/check_batch_cost_job.py` |
|
||||
| `check_responses_cost` | 30min | Calculate costs for responses API | `proxy/management_helpers/check_responses_cost_job.py` |
|
||||
| `process_rotations` | 1hr | Auto-rotate API keys | `proxy/management_helpers/key_rotation_manager.py` |
|
||||
| `_run_background_health_check` | continuous | Health check model deployments | `proxy/proxy_server.py` |
|
||||
| `send_weekly_spend_report` | weekly | Slack spend alerts | `proxy/utils.py` (`SlackAlerting`) |
|
||||
| `send_monthly_spend_report` | monthly | Slack spend alerts | `proxy/utils.py` (`SlackAlerting`) |
|
||||
|
||||
**Cost Attribution Flow:**
|
||||
1. LLM response returns to `utils.py` wrapper after `litellm.acompletion()` completes
|
||||
2. `update_response_metadata()` (`llm_response_utils/response_metadata.py`) is called
|
||||
3. `logging_obj._response_cost_calculator()` (`litellm_logging.py`) calculates cost via `litellm.completion_cost()` (`cost_calculator.py`)
|
||||
4. Cost is stored in `response._hidden_params["response_cost"]`
|
||||
5. `proxy/common_request_processing.py` extracts cost from `hidden_params` and adds to response headers (`x-litellm-response-cost`)
|
||||
6. `logging_obj.async_success_handler()` triggers callbacks including `_ProxyDBLogger.async_log_success_event()`
|
||||
7. `DBSpendUpdateWriter.update_database()` queues spend increments to Redis
|
||||
8. Background job `update_spend` flushes queued spend to PostgreSQL every 60s
|
||||
|
||||
---
|
||||
|
||||
## 2. SDK Request Flow
|
||||
|
|
|
|||
|
|
@ -1,4 +0,0 @@
|
|||
{"custom_id": "request-1", "method": "POST", "url": "/v1/chat/completions", "body": {"model": "gpt-3.5-turbo", "messages": [{"role": "user", "content": "Hello, how are you?"}]}}
|
||||
{"custom_id": "request-2", "method": "POST", "url": "/v1/chat/completions", "body": {"model": "gpt-3.5-turbo", "messages": [{"role": "user", "content": "What is the weather today?"}]}}
|
||||
{"custom_id": "request-3", "method": "POST", "url": "/v1/chat/completions", "body": {"model": "gpt-3.5-turbo", "messages": [{"role": "user", "content": "Tell me a short joke"}]}}
|
||||
|
||||
|
|
@ -1,3 +1,3 @@
|
|||
ignore:
|
||||
- vulnerability: CVE-2019-1010022
|
||||
reason: no fixed glibc package is available yet in the Wolfi repositories, so this is ignored temporarily until an upstream release exists
|
||||
- vulnerability: CVE-2026-22184
|
||||
reason: no fixed zlib package is available yet in the Wolfi repositories, so this is ignored temporarily until an upstream release exists
|
||||
|
|
|
|||
|
|
@ -129,11 +129,14 @@ run_grype_scans() {
|
|||
"CVE-2025-13836" # Python 3.13 HTTP response reading OOM/DoS - no fix available in base image
|
||||
"CVE-2025-12084" # Python 3.13 xml.dom.minidom quadratic algorithm - no fix available in base image
|
||||
"CVE-2025-60876" # BusyBox wget HTTP request splitting - no fix available in Chainguard Wolfi base image
|
||||
"CVE-2026-0861" # Wolfi glibc still flagged even on 2.42-r5; upstream patched build unavailable yet
|
||||
"CVE-2010-4756" # glibc glob DoS - awaiting patched Wolfi glibc build
|
||||
"CVE-2019-1010022" # glibc stack guard bypass - awaiting patched Wolfi glibc build
|
||||
"CVE-2019-1010023" # glibc ldd remap issue - awaiting patched Wolfi glibc build
|
||||
"CVE-2019-1010024" # glibc ASLR mitigation bypass - awaiting patched Wolfi glibc build
|
||||
"CVE-2019-1010025" # glibc pthread heap address leak - awaiting patched Wolfi glibc build
|
||||
"CVE-2026-22184" # zlib untgz buffer overflow - untgz unused + no fixed Wolfi build yet
|
||||
"GHSA-58pv-8j8x-9vj2" # jaraco.context path traversal - setuptools vendored only (v5.3.0), not used in application code (using v6.1.0+)
|
||||
)
|
||||
|
||||
# Build JSON array of allowlisted CVE IDs for jq
|
||||
|
|
|
|||
|
|
@ -20,4 +20,79 @@
|
|||
"LiteLLM",
|
||||
"MCP"
|
||||
]
|
||||
},
|
||||
{
|
||||
"title": "Claude Code with Non-Anthropic Models",
|
||||
"description": "This is a guide to using Claude Code with non-Anthropic models via LiteLLM Proxy.",
|
||||
"url": "https://docs.litellm.ai/docs/tutorials/claude_non_anthropic_models",
|
||||
"date": "2026-01-16",
|
||||
"version": "1.0.0",
|
||||
"tags": [
|
||||
"Claude Code",
|
||||
"LiteLLM",
|
||||
"OpenAI",
|
||||
"Gemini"
|
||||
]
|
||||
},
|
||||
{
|
||||
"title": "Cursor Quickstart",
|
||||
"description": "This is a quickstart guide to using Cursor with LiteLLM.",
|
||||
"url": "https://docs.litellm.ai/docs/tutorials/cursor_integration",
|
||||
"date": "2026-01-16",
|
||||
"version": "1.0.0",
|
||||
"tags": [
|
||||
"Cursor",
|
||||
"LiteLLM",
|
||||
"Quickstart"
|
||||
]
|
||||
},
|
||||
{
|
||||
"title": "Github Copilot Quickstart",
|
||||
"description": "This is a quickstart guide to using Github Copilot with LiteLLM.",
|
||||
"url": "https://docs.litellm.ai/docs/tutorials/github_copilot_integration",
|
||||
"date": "2026-01-16",
|
||||
"version": "1.0.0",
|
||||
"tags": [
|
||||
"Github Copilot",
|
||||
"LiteLLM",
|
||||
"Quickstart"
|
||||
]
|
||||
},
|
||||
{
|
||||
"title": "LiteLLM Gemini CLI Quickstart",
|
||||
"description": "This is a quickstart guide to using LiteLLM Gemini CLI.",
|
||||
"url": "https://docs.litellm.ai/docs/tutorials/litellm_gemini_cli",
|
||||
"date": "2026-01-16",
|
||||
"version": "1.0.0",
|
||||
"tags": [
|
||||
"Gemini CLI",
|
||||
"Gemini",
|
||||
"LiteLLM",
|
||||
"Quickstart"
|
||||
]
|
||||
},
|
||||
{
|
||||
"title": "OpenAI Codex CLI Quickstart",
|
||||
"description": "This is a quickstart guide to using OpenAI Codex CLI.",
|
||||
"url": "https://docs.litellm.ai/docs/tutorials/openai_codex",
|
||||
"date": "2026-01-16",
|
||||
"version": "1.0.0",
|
||||
"tags": [
|
||||
"OpenAI Codex CLI",
|
||||
"OpenAI",
|
||||
"LiteLLM",
|
||||
"Quickstart"
|
||||
]
|
||||
},
|
||||
{
|
||||
"title": "OpenWebUI Quickstart",
|
||||
"description": "This is a quickstart guide to using OpenWebUI with LiteLLM.",
|
||||
"url": "https://docs.litellm.ai/docs/tutorials/openweb_ui",
|
||||
"date": "2026-01-16",
|
||||
"version": "1.0.0",
|
||||
"tags": [
|
||||
"OpenWebUI",
|
||||
"LiteLLM",
|
||||
"Quickstart"
|
||||
]
|
||||
}]
|
||||
|
|
@ -105,6 +105,14 @@ Then simply initialize:
|
|||
litellm.cache = Cache(type="redis")
|
||||
```
|
||||
|
||||
:::info
|
||||
Use `REDIS_*` environment variables as the primary mechanism for configuring all Redis client library parameters. This approach automatically maps environment variables to Redis client kwargs and is the suggested way to toggle Redis settings.
|
||||
:::
|
||||
|
||||
:::warning
|
||||
If you need to pass non-string Redis parameters (integers, booleans, complex objects), avoid `REDIS_*` environment variables as they may fail during Redis client initialization. Instead, pass them directly as kwargs to the `Cache()` constructor.
|
||||
:::
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="gcs" label="gcs-cache">
|
||||
|
|
|
|||
|
|
@ -40,6 +40,10 @@ import os
|
|||
# from https://logfire.pydantic.dev/
|
||||
os.environ["LOGFIRE_TOKEN"] = ""
|
||||
|
||||
# Optionally customize the base url
|
||||
# from https://logfire.pydantic.dev/
|
||||
os.environ["LOGFIRE_BASE_URL"] = ""
|
||||
|
||||
# LLM API Keys
|
||||
os.environ['OPENAI_API_KEY']=""
|
||||
|
||||
|
|
|
|||
|
|
@ -12,100 +12,340 @@ LiteLLM supports SAP Generative AI Hub's Orchestration Service.
|
|||
| Supported Endpoints | `/chat/completions`, `/embeddings` |
|
||||
| API Reference | [SAP AI Core Documentation](https://help.sap.com/docs/sap-ai-core) |
|
||||
|
||||
## Prerequisites
|
||||
|
||||
Before you begin, ensure you have:
|
||||
|
||||
1. **SAP BTP Account** with access to SAP AI Core
|
||||
2. **AI Core Service Instance** provisioned in your subaccount
|
||||
3. **Service Key** created for your AI Core instance (this contains your credentials)
|
||||
4. **Resource Group** with deployed AI models (check with your SAP administrator)
|
||||
|
||||
:::tip Where to Find Your Credentials
|
||||
Your credentials come from the **Service Key** you create in SAP BTP Cockpit:
|
||||
|
||||
1. Navigate to your **Subaccount** → **Instances and Subscriptions**
|
||||
2. Find your **AI Core** instance and click on it
|
||||
3. Go to **Service Keys** and create one (or use existing)
|
||||
4. The JSON contains all values needed below
|
||||
|
||||
The service key JSON looks like this:
|
||||
|
||||
```json
|
||||
{
|
||||
"clientid": "sb-abc123...",
|
||||
"clientsecret": "xyz789...",
|
||||
"url": "https://myinstance.authentication.eu10.hana.ondemand.com",
|
||||
"serviceurls": {
|
||||
"AI_API_URL": "https://api.ai.prod.eu-central-1.aws.ml.hana.ondemand.com"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
:::info Resource Group
|
||||
The resource group is typically configured separately in your AI Core deployment, not in the service key itself. You can set it via the `AICORE_RESOURCE_GROUP` environment variable (defaults to "default").
|
||||
:::
|
||||
|
||||
## Quick Start
|
||||
|
||||
### Step 1: Install LiteLLM
|
||||
|
||||
```bash
|
||||
pip install litellm
|
||||
```
|
||||
|
||||
### Step 2: Set Your Credentials
|
||||
|
||||
Choose **one** of these authentication methods:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="service-key" label="Service Key JSON (Recommended)">
|
||||
|
||||
The simplest approach - paste your entire service key as a single environment variable. The service key must be wrapped in a `credentials` object:
|
||||
|
||||
```bash
|
||||
export AICORE_SERVICE_KEY='{
|
||||
"credentials": {
|
||||
"clientid": "your-client-id",
|
||||
"clientsecret": "your-client-secret",
|
||||
"url": "https://<your-instance>.authentication.sap.hana.ondemand.com",
|
||||
"serviceurls": {
|
||||
"AI_API_URL": "https://api.ai.<your-region>.aws.ml.hana.ondemand.com"
|
||||
}
|
||||
}
|
||||
}'
|
||||
export AICORE_RESOURCE_GROUP="default"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="individual" label="Individual Variables">
|
||||
|
||||
Alternatively, instead of using the service key above, you could set each credential separately:
|
||||
|
||||
```bash
|
||||
export AICORE_AUTH_URL="https://<your-instance>.authentication.sap.hana.ondemand.com/oauth/token"
|
||||
export AICORE_CLIENT_ID="your-client-id"
|
||||
export AICORE_CLIENT_SECRET="your-client-secret"
|
||||
export AICORE_RESOURCE_GROUP="default"
|
||||
export AICORE_BASE_URL="https://api.ai.<your-region>.aws.ml.hana.ondemand.com/v2"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Step 3: Make Your First Request
|
||||
|
||||
```python title="test_sap.py"
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="sap/gpt-4o",
|
||||
messages=[{"role": "user", "content": "Hello from LiteLLM!"}]
|
||||
)
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
Run it:
|
||||
|
||||
```bash
|
||||
python test_sap.py
|
||||
```
|
||||
|
||||
**Expected output:**
|
||||
|
||||
```text
|
||||
Hello! How can I assist you today?
|
||||
```
|
||||
|
||||
### Step 4: Verify Your Setup (Optional)
|
||||
|
||||
Test that everything is working with this diagnostic script:
|
||||
|
||||
```python title="verify_sap_setup.py"
|
||||
import os
|
||||
import litellm
|
||||
|
||||
# Enable debug logging to see what's happening
|
||||
import os
|
||||
os.environ["LITELLM_LOG"] = "DEBUG"
|
||||
|
||||
# Either use AICORE_SERVICE_KEY (contains all credentials including resourcegroup)
|
||||
# OR use individual variables (all required together)
|
||||
individual_vars = ["AICORE_AUTH_URL", "AICORE_CLIENT_ID", "AICORE_CLIENT_SECRET", "AICORE_BASE_URL", "AICORE_RESOURCE_GROUP"]
|
||||
|
||||
print("=== SAP Gen AI Hub Setup Verification ===\n")
|
||||
|
||||
# Check for service key method
|
||||
if os.environ.get("AICORE_SERVICE_KEY"):
|
||||
print("✓ Using AICORE_SERVICE_KEY authentication (includes resource group)")
|
||||
else:
|
||||
# Check individual variables
|
||||
missing = [v for v in individual_vars if not os.environ.get(v)]
|
||||
if missing:
|
||||
print(f"✗ Missing environment variables: {missing}")
|
||||
else:
|
||||
print("✓ Using individual variable authentication")
|
||||
print(f"✓ Resource group: {os.environ.get('AICORE_RESOURCE_GROUP')}")
|
||||
|
||||
# Test API connection
|
||||
print("\n=== Testing API Connection ===\n")
|
||||
try:
|
||||
response = litellm.completion(
|
||||
model="sap/gpt-4o",
|
||||
messages=[{"role": "user", "content": "Say 'Connection successful!' and nothing else."}],
|
||||
max_tokens=20
|
||||
)
|
||||
print(f"✓ API Response: {response.choices[0].message.content}")
|
||||
print("\n🎉 Setup complete! You're ready to use SAP Gen AI Hub with LiteLLM.")
|
||||
except Exception as e:
|
||||
print(f"✗ API Error: {e}")
|
||||
print("\nTroubleshooting tips:")
|
||||
print(" 1. Verify your service key credentials are correct")
|
||||
print(" 2. Check that 'gpt-4o' is deployed in your resource group")
|
||||
print(" 3. Ensure your SAP AI Core instance is running")
|
||||
```
|
||||
|
||||
Run the verification:
|
||||
|
||||
```bash
|
||||
python verify_sap_setup.py
|
||||
```
|
||||
|
||||
**Expected output on success:**
|
||||
|
||||
```text
|
||||
=== SAP Gen AI Hub Setup Verification ===
|
||||
|
||||
✓ Using AICORE_SERVICE_KEY authentication
|
||||
✓ Resource group: default
|
||||
|
||||
=== Testing API Connection ===
|
||||
|
||||
✓ API Response: Connection successful!
|
||||
|
||||
🎉 Setup complete! You're ready to use SAP Gen AI Hub with LiteLLM.
|
||||
```
|
||||
|
||||
## Authentication
|
||||
|
||||
SAP Generative AI Hub uses service key authentication. You can provide credentials via:
|
||||
SAP Generative AI Hub uses OAuth2 service keys for authentication. See [Quick Start](#quick-start) for setup instructions.
|
||||
|
||||
1. **Environment variable** - Set `AICORE_SERVICE_KEY` with your service key JSON
|
||||
2. **Direct parameter** - Pass `api_key` with the service key JSON string
|
||||
### Environment Variables Reference
|
||||
|
||||
```python showLineNumbers title="Environment Variable"
|
||||
import os
|
||||
os.environ["AICORE_SERVICE_KEY"] = '{"clientid": "...", "clientsecret": "...", ...}'
|
||||
| Variable | Required | Description |
|
||||
|----------|----------|-------------|
|
||||
| `AICORE_SERVICE_KEY` | Yes* | Complete service key JSON (recommended method) |
|
||||
| `AICORE_RESOURCE_GROUP` | Yes | Your AI Core resource group name |
|
||||
| `AICORE_AUTH_URL` | Yes* | OAuth token URL (alternative to service key) |
|
||||
| `AICORE_CLIENT_ID` | Yes* | OAuth client ID (alternative to service key) |
|
||||
| `AICORE_CLIENT_SECRET` | Yes* | OAuth client secret (alternative to service key) |
|
||||
| `AICORE_BASE_URL` | Yes* | AI Core API base URL (alternative to service key) |
|
||||
|
||||
*Choose either `AICORE_SERVICE_KEY` OR the individual variables (`AICORE_AUTH_URL`, `AICORE_CLIENT_ID`, `AICORE_CLIENT_SECRET`, `AICORE_BASE_URL`).
|
||||
|
||||
## Model Naming Conventions
|
||||
|
||||
Understanding model naming is crucial for using SAP Gen AI Hub correctly. The naming pattern differs depending on whether you're using the SDK directly or through the proxy.
|
||||
|
||||
### Direct SDK Usage
|
||||
|
||||
When calling LiteLLM's SDK directly, you **must** include the `sap/` prefix in the model name:
|
||||
|
||||
```python
|
||||
# Correct - includes sap/ prefix
|
||||
model="sap/gpt-4o"
|
||||
model="sap/anthropic--claude-4.5-sonnet"
|
||||
model="sap/gemini-2.5-pro"
|
||||
|
||||
# Incorrect - missing prefix
|
||||
model="gpt-4o" # ❌ Won't work
|
||||
```
|
||||
3. **Environment variables** - Set the following list of credentials in .env file
|
||||
<pre>
|
||||
AICORE_AUTH_URL = "https://* * * .authentication.sap.hana.ondemand.com/oauth/token",
|
||||
AICORE_CLIENT_ID = " *** ",
|
||||
AICORE_CLIENT_SECRET = " *** ",
|
||||
AICORE_RESOURCE_GROUP = " *** ",
|
||||
AICORE_BASE_URL = "https://api.ai.***.cfapps.sap.hana.ondemand.com/v2"
|
||||
</pre>
|
||||
## Usage - LiteLLM Python SDK
|
||||
|
||||
```python showLineNumbers title="SAP Chat Completion"
|
||||
from litellm import completion
|
||||
import os
|
||||
### Proxy Usage
|
||||
|
||||
os.environ["AICORE_SERVICE_KEY"] = '{"clientid": "...", "clientsecret": "...", ...}'
|
||||
When using the LiteLLM Proxy, you use the **friendly `model_name`** defined in your configuration. The proxy automatically handles the `sap/` prefix routing.
|
||||
|
||||
response = completion(
|
||||
model="sap/gpt-4",
|
||||
messages=[{"role": "user", "content": "Hello from LiteLLM"}]
|
||||
```yaml
|
||||
# In config.yaml, define the mapping
|
||||
model_list:
|
||||
- model_name: gpt-4o # ← Use this name in client requests
|
||||
litellm_params:
|
||||
model: sap/gpt-4o # ← Proxy handles the sap/ prefix
|
||||
```
|
||||
|
||||
```python
|
||||
# Client request - no sap/ prefix needed
|
||||
client.chat.completions.create(
|
||||
model="gpt-4o", # ✓ Correct for proxy usage
|
||||
messages=[...]
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
```python showLineNumbers title="SAP Chat Completion - Streaming"
|
||||
### Anthropic Models Special Syntax
|
||||
|
||||
Anthropic models use a double-dash (`--`) prefix convention:
|
||||
|
||||
| Provider | Model Example | LiteLLM Format |
|
||||
|----------|---------------|----------------|
|
||||
| OpenAI | GPT-4o | `sap/gpt-4o` |
|
||||
| Anthropic | Claude 4.5 Sonnet | `sap/anthropic--claude-4.5-sonnet` |
|
||||
| Google | Gemini 2.5 Pro | `sap/gemini-2.5-pro` |
|
||||
| Mistral | Mistral Large | `sap/mistral-large` |
|
||||
|
||||
### Quick Reference Table
|
||||
|
||||
| Usage Type | Model Format | Example |
|
||||
|------------|--------------|---------|
|
||||
| Direct SDK | `sap/<model-name>` | `sap/gpt-4o` |
|
||||
| Direct SDK (Anthropic) | `sap/anthropic--<model>` | `sap/anthropic--claude-4.5-sonnet` |
|
||||
| Proxy Client | `<friendly-name>` | `gpt-4o` or `claude-sonnet` |
|
||||
|
||||
## Using the Python SDK
|
||||
|
||||
The LiteLLM Python SDK automatically detects your authentication method. Simply set your environment variables and make requests.
|
||||
|
||||
```python showLineNumbers title="Basic Completion"
|
||||
from litellm import completion
|
||||
import os
|
||||
|
||||
os.environ["AICORE_SERVICE_KEY"] = '{"clientid": "...", "clientsecret": "...", ...}'
|
||||
|
||||
# Assumes AICORE_AUTH_URL, AICORE_CLIENT_ID, etc. are set
|
||||
response = completion(
|
||||
model="sap/gpt-4",
|
||||
messages=[{"role": "user", "content": "Hello from LiteLLM"}],
|
||||
stream=True
|
||||
model="sap/anthropic--claude-4.5-sonnet",
|
||||
messages=[{"role": "user", "content": "Explain quantum computing"}]
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
print(chunk.choices[0].delta.content or "", end="")
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
```python showLineNumbers title="SAP Embedding"
|
||||
from litellm import embedding
|
||||
import os
|
||||
Both authentication methods (individual variables or service key JSON) work automatically - no code changes required.
|
||||
|
||||
os.environ["AICORE_SERVICE_KEY"] = '{"clientid": "...", "clientsecret": "...", ...}'
|
||||
## Using the Proxy Server
|
||||
|
||||
result = embedding(
|
||||
model="sap/text-embedding-3-small",
|
||||
input="Answer to the ultimate question of life, the universe, and everything is 42")
|
||||
print(result.data[0])
|
||||
```
|
||||
The LiteLLM Proxy provides a unified OpenAI-compatible API for your SAP models.
|
||||
|
||||
## Usage - LiteLLM Proxy
|
||||
### Configuration
|
||||
|
||||
Add to your LiteLLM Proxy config:
|
||||
Create a `config.yaml` file in your project directory with your model mappings and credentials:
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
model_list:
|
||||
- model_name: "sap/*"
|
||||
# OpenAI models
|
||||
- model_name: gpt-5
|
||||
litellm_params:
|
||||
model: "sap/*"
|
||||
model: sap/gpt-5
|
||||
|
||||
general_settings:
|
||||
master_key: your-proxy-api-key
|
||||
# Anthropic models (note the double-dash)
|
||||
- model_name: claude-sonnet
|
||||
litellm_params:
|
||||
model: sap/anthropic--claude-4.5-sonnet
|
||||
|
||||
- model_name: claude-opus
|
||||
litellm_params:
|
||||
model: sap/anthropic--claude-4.5-opus
|
||||
|
||||
# Embeddings
|
||||
- model_name: text-embedding-3-small
|
||||
litellm_params:
|
||||
model: sap/text-embedding-3-small
|
||||
|
||||
litellm_settings:
|
||||
drop_params: true
|
||||
set_verbose: false
|
||||
request_timeout: 600
|
||||
num_retries: 2
|
||||
forward_client_headers_to_llm_api: ["anthropic-version"]
|
||||
|
||||
general_settings:
|
||||
master_key: "sk-1234" # Enter here your desired master key starting with 'sk-'.
|
||||
|
||||
# UI Admin is not required but helpful including the management of keys for your team(s). If you are using a database, these parameters are required:
|
||||
database_url: "Enter you database URL."
|
||||
UI_USERNAME: "Your desired UI admin account name"
|
||||
UI_PASSWORD: "Your desired and strong pwd"
|
||||
|
||||
# Authentication
|
||||
environment_variables:
|
||||
AICORE_SERVICE_KEY: '{"clientid": "...", "clientsecret": "...", ...}'
|
||||
AICORE_SERVICE_KEY: '{"credentials": {"clientid": "...", "clientsecret": "...", "url": "...", "serviceurls": {"AI_API_URL": "..."}}}'
|
||||
AICORE_RESOURCE_GROUP: "default"
|
||||
```
|
||||
|
||||
Start the proxy:
|
||||
### Starting the Proxy
|
||||
|
||||
```bash showLineNumbers title="Start Proxy"
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
The proxy will start on `http://localhost:4000` by default.
|
||||
|
||||
### Making Requests
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="curl" label="cURL">
|
||||
|
||||
```bash showLineNumbers title="Test Request"
|
||||
curl http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer your-proxy-api-key" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "sap/gpt-4",
|
||||
"model": "gpt-4o",
|
||||
"messages": [{"role": "user", "content": "Hello"}]
|
||||
}'
|
||||
```
|
||||
|
|
@ -118,11 +358,11 @@ from openai import OpenAI
|
|||
|
||||
client = OpenAI(
|
||||
base_url="http://localhost:4000",
|
||||
api_key="your-proxy-api-key"
|
||||
api_key="sk-1234"
|
||||
)
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="sap/gpt-4",
|
||||
model="gpt-4o",
|
||||
messages=[{"role": "user", "content": "Hello"}]
|
||||
)
|
||||
print(response.choices[0].message.content)
|
||||
|
|
@ -134,12 +374,14 @@ print(response.choices[0].message.content)
|
|||
```python showLineNumbers title="LiteLLM SDK"
|
||||
import os
|
||||
import litellm
|
||||
os.environ["LITELLM_PROXY_API_KEY"] = "your-proxy-api-key"
|
||||
litellm.use_litellm_proxy = True # it is important to set this parameter
|
||||
|
||||
os.environ["LITELLM_PROXY_API_KEY"] = "sk-1234"
|
||||
litellm.use_litellm_proxy = True
|
||||
|
||||
response = litellm.completion(
|
||||
model="sap/gpt-4o",
|
||||
messages=[{ "content": "Hello, how are you?","role": "user"}],
|
||||
api_base="http://your-proxy-api-base"
|
||||
model="claude-sonnet",
|
||||
messages=[{"content": "Hello, how are you?", "role": "user"}],
|
||||
api_base="http://localhost:4000"
|
||||
)
|
||||
|
||||
print(response)
|
||||
|
|
@ -148,15 +390,170 @@ print(response)
|
|||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Supported Parameters
|
||||
## Features
|
||||
|
||||
| Parameter | Description |
|
||||
|-----------|-------------|
|
||||
| `temperature` | Controls randomness |
|
||||
| `max_tokens` | Maximum tokens in response |
|
||||
| `top_p` | Nucleus sampling |
|
||||
| `tools` | Function calling tools |
|
||||
| `tool_choice` | Tool selection behavior |
|
||||
| `response_format` | Output format (json_object, json_schema) |
|
||||
| `stream` | Enable streaming |
|
||||
### Streaming Responses
|
||||
|
||||
Stream responses in real-time for better user experience:
|
||||
|
||||
```python showLineNumbers title="Streaming Chat Completion"
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="sap/gpt-4o",
|
||||
messages=[{"role": "user", "content": "Count from 1 to 10"}],
|
||||
stream=True
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
if chunk.choices[0].delta.content:
|
||||
print(chunk.choices[0].delta.content, end="", flush=True)
|
||||
```
|
||||
|
||||
### Structured Output
|
||||
|
||||
#### JSON Schema (Recommended)
|
||||
|
||||
Use JSON Schema for structured output with strict validation:
|
||||
|
||||
```python showLineNumbers title="JSON Schema Response"
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="sap/gpt-4o",
|
||||
messages=[{
|
||||
"role": "user",
|
||||
"content": "Generate info about Tokyo"
|
||||
}],
|
||||
response_format={
|
||||
"type": "json_schema",
|
||||
"json_schema": {
|
||||
"name": "city_info",
|
||||
"schema": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"name": {"type": "string"},
|
||||
"population": {"type": "number"},
|
||||
"country": {"type": "string"}
|
||||
},
|
||||
"required": ["name", "population", "country"],
|
||||
"additionalProperties": False
|
||||
},
|
||||
"strict": True
|
||||
}
|
||||
}
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
# Output: {"name":"Tokyo","population":37000000,"country":"Japan"}
|
||||
```
|
||||
|
||||
#### JSON Object Format
|
||||
|
||||
For flexible JSON output without schema validation:
|
||||
|
||||
```python showLineNumbers title="JSON Object Response"
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="sap/gpt-4o",
|
||||
messages=[{
|
||||
"role": "user",
|
||||
"content": "Generate a person object in JSON format with name and age"
|
||||
}],
|
||||
response_format={"type": "json_object"}
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
:::note SAP Platform Requirement
|
||||
When using `json_object` type, SAP's orchestration service requires the word "json" to appear in your prompt. This ensures explicit intent for JSON formatting. For schema-validated output without this requirement, use `json_schema` instead (recommended).
|
||||
:::
|
||||
|
||||
### Multi-turn Conversations
|
||||
|
||||
Maintain conversation context across multiple turns:
|
||||
|
||||
```python showLineNumbers title="Multi-turn Conversation"
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="sap/gpt-4o",
|
||||
messages=[
|
||||
{"role": "user", "content": "My name is Alice"},
|
||||
{"role": "assistant", "content": "Hello Alice! Nice to meet you."},
|
||||
{"role": "user", "content": "What is my name?"}
|
||||
]
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
# Output: Your name is Alice.
|
||||
```
|
||||
|
||||
### Embeddings
|
||||
|
||||
Generate vector embeddings for semantic search and retrieval:
|
||||
|
||||
```python showLineNumbers title="Create Embeddings"
|
||||
from litellm import embedding
|
||||
|
||||
response = embedding(
|
||||
model="sap/text-embedding-3-small",
|
||||
input=["Hello world", "Machine learning is fascinating"]
|
||||
)
|
||||
|
||||
print(response.data[0]["embedding"]) # Vector representation
|
||||
```
|
||||
|
||||
## Reference
|
||||
|
||||
### Supported Parameters
|
||||
|
||||
| Parameter | Type | Description |
|
||||
|-----------|------|-------------|
|
||||
| `model` | string | Model identifier (with `sap/` prefix for SDK) |
|
||||
| `messages` | array | Conversation messages |
|
||||
| `temperature` | float | Controls randomness (0-2) |
|
||||
| `max_tokens` | integer | Maximum tokens in response |
|
||||
| `top_p` | float | Nucleus sampling threshold |
|
||||
| `stream` | boolean | Enable streaming responses |
|
||||
| `response_format` | object | Output format (`json_object`, `json_schema`) |
|
||||
| `tools` | array | Function calling tool definitions |
|
||||
| `tool_choice` | string/object | Tool selection behavior |
|
||||
|
||||
### Supported Models
|
||||
|
||||
For the complete and up-to-date list of available models provided by SAP Gen AI Hub, please refer to the [SAP AI Core Generative AI Hub documentation](https://help.sap.com/docs/sap-ai-core/sap-ai-core-service-guide/models-and-scenarios-in-generative-ai-hub).
|
||||
|
||||
:::info Model Availability
|
||||
Model availability varies by SAP deployment region and your subscription. Contact your SAP administrator to confirm which models are available in your environment.
|
||||
:::
|
||||
|
||||
### Troubleshooting
|
||||
|
||||
**Authentication Errors**
|
||||
|
||||
If you receive authentication errors:
|
||||
|
||||
1. Verify all required environment variables are set correctly
|
||||
2. Check that your service key hasn't expired
|
||||
3. Confirm your resource group has access to the desired models
|
||||
4. Ensure the `AICORE_AUTH_URL` and `AICORE_BASE_URL` match your SAP region
|
||||
|
||||
**Model Not Found**
|
||||
|
||||
If a model returns "not found":
|
||||
|
||||
1. Verify the model is available in your SAP deployment
|
||||
2. Check you're using the correct model name format (`sap/` prefix for SDK)
|
||||
3. Confirm your resource group has access to that specific model
|
||||
4. For Anthropic models, ensure you're using the `anthropic--` double-dash prefix
|
||||
|
||||
**Rate Limiting**
|
||||
|
||||
SAP Gen AI Hub enforces rate limits based on your subscription. If you hit limits:
|
||||
|
||||
1. Implement exponential backoff retry logic
|
||||
2. Consider using the proxy's built-in rate limiting features
|
||||
3. Contact your SAP administrator to review quota allocations
|
||||
|
|
|
|||
|
|
@ -416,7 +416,6 @@ response = image_edit(
|
|||
image=open("original_image.png", "rb"),
|
||||
mask=open("mask_image.png", "rb"),
|
||||
prompt="Add flowers in the masked area",
|
||||
size="1024x1024",
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
|
|
|||
|
|
@ -282,6 +282,10 @@ Set either `REDIS_URL` or the `REDIS_HOST` in your os environment, to enable cac
|
|||
```
|
||||
|
||||
**Additional kwargs**
|
||||
:::info
|
||||
Use `REDIS_*` environment variables to configure all Redis client library parameters. This is the suggested mechanism for toggling Redis settings as it automatically maps environment variables to Redis client kwargs.
|
||||
:::
|
||||
|
||||
You can pass in any additional redis.Redis arg, by storing the variable + value in your os
|
||||
environment, like this:
|
||||
|
||||
|
|
@ -289,6 +293,17 @@ environment, like this:
|
|||
REDIS_<redis-kwarg-name> = ""
|
||||
```
|
||||
|
||||
For example:
|
||||
```shell
|
||||
REDIS_SSL = "True"
|
||||
REDIS_SSL_CERT_REQS = "None"
|
||||
REDIS_CONNECTION_POOL_KWARGS = '{"max_connections": 20}'
|
||||
```
|
||||
|
||||
:::warning
|
||||
**Note**: For non-string Redis parameters (like integers, booleans, or complex objects), avoid using `REDIS_*` environment variables as they may fail during Redis client initialization. Instead, use `cache_kwargs` in your router configuration for such parameters.
|
||||
:::
|
||||
|
||||
[**See how it's read from the environment**](https://github.com/BerriAI/litellm/blob/4d7ff1b33b9991dcf38d821266290631d9bcd2dd/litellm/_redis.py#L40)
|
||||
|
||||
#### Step 3: Run proxy with config
|
||||
|
|
|
|||
|
|
@ -339,7 +339,7 @@ router_settings:
|
|||
| stream_timeout | Optional[float] | The default timeout for a streaming request. If not set, the 'timeout' value is used. |
|
||||
| debug_level | Literal["DEBUG", "INFO"] | The debug level for the logging library in the router. Defaults to "INFO". |
|
||||
| client_ttl | int | Time-to-live for cached clients in seconds. Defaults to 3600. |
|
||||
| cache_kwargs | dict | Additional keyword arguments for the cache initialization. |
|
||||
| cache_kwargs | dict | Additional keyword arguments for the cache initialization. Use this for non-string Redis parameters that may fail when set via `REDIS_*` environment variables. |
|
||||
| routing_strategy_args | dict | Additional keyword arguments for the routing strategy - e.g. lowest latency routing default ttl |
|
||||
| model_group_alias | dict | Model group alias mapping. E.g. `{"claude-3-haiku": "claude-3-haiku-20240229"}` |
|
||||
| num_retries | int | Number of retries for a request. Defaults to 3. |
|
||||
|
|
@ -744,6 +744,7 @@ router_settings:
|
|||
| LITELLM_PRINT_STANDARD_LOGGING_PAYLOAD | If true, prints the standard logging payload to the console - useful for debugging
|
||||
| LITELM_ENVIRONMENT | Environment for LiteLLM Instance. This is currently only logged to DeepEval to determine the environment for DeepEval integration.
|
||||
| LOGFIRE_TOKEN | Token for Logfire logging service
|
||||
| LOGFIRE_BASE_URL | Base URL for Logfire logging service (useful for self hosted deployments)
|
||||
| LOGGING_WORKER_CONCURRENCY | Maximum number of concurrent coroutine slots for the logging worker on the asyncio event loop. Default is 100. Setting too high will flood the event loop with logging tasks which will lower the overall latency of the requests.
|
||||
| LOGGING_WORKER_MAX_QUEUE_SIZE | Maximum size of the logging worker queue. When the queue is full, the worker aggressively clears tasks to make room instead of dropping logs. Default is 50,000
|
||||
| LOGGING_WORKER_MAX_TIME_PER_COROUTINE | Maximum time in seconds allowed for each coroutine in the logging worker before timing out. Default is 20.0
|
||||
|
|
@ -754,6 +755,7 @@ router_settings:
|
|||
| LOGGING_WORKER_AGGRESSIVE_CLEAR_COOLDOWN_SECONDS | Cooldown time in seconds before allowing another aggressive clear operation when the queue is full. Default is 0.5
|
||||
| MAX_STRING_LENGTH_PROMPT_IN_DB | Maximum length for strings in spend logs when sanitizing request bodies. Strings longer than this will be truncated. Default is 1000
|
||||
| MAX_IN_MEMORY_QUEUE_FLUSH_COUNT | Maximum count for in-memory queue flush operations. Default is 1000
|
||||
| MAX_IMAGE_URL_DOWNLOAD_SIZE_MB | Maximum size in MB for downloading images from URLs. Prevents memory issues from downloading very large images. Images exceeding this limit will be rejected before download. Set to 0 to completely disable image URL handling (all image_url requests will be blocked). Default is 50MB (matching [OpenAI's limit](https://platform.openai.com/docs/guides/images-vision?api-mode=chat#image-input-requirements))
|
||||
| MAX_LONG_SIDE_FOR_IMAGE_HIGH_RES | Maximum length for the long side of high-resolution images. Default is 2000
|
||||
| MAX_REDIS_BUFFER_DEQUEUE_COUNT | Maximum count for Redis buffer dequeue operations. Default is 100
|
||||
| MAX_SHORT_SIDE_FOR_IMAGE_HIGH_RES | Maximum length for the short side of high-resolution images. Default is 768
|
||||
|
|
|
|||
|
|
@ -9,7 +9,6 @@ LiteLLM provides flexible cost tracking and pricing customization for all LLM pr
|
|||
- **Custom Pricing** - Override default model costs or set pricing for custom models
|
||||
- **Cost Per Token** - Track costs based on input/output tokens (most common)
|
||||
- **Cost Per Second** - Track costs based on runtime (e.g., Sagemaker)
|
||||
- **Zero-Cost Models** - Bypass budget checks for free/on-premises models by setting costs to 0
|
||||
- **[Provider Discounts](./provider_discounts.md)** - Apply percentage-based discounts to specific providers
|
||||
- **[Provider Margins](./provider_margins.md)** - Add fees/margins to LLM costs for internal billing
|
||||
- **Base Model Mapping** - Ensure accurate cost tracking for Azure deployments
|
||||
|
|
@ -107,51 +106,6 @@ There are other keys you can use to specify costs for different scenarios and mo
|
|||
|
||||
These keys evolve based on how new models handle multimodality. The latest version can be found at [https://github.com/BerriAI/litellm/blob/main/model_prices_and_context_window.json](https://github.com/BerriAI/litellm/blob/main/model_prices_and_context_window.json).
|
||||
|
||||
## Zero-Cost Models (Bypass Budget Checks)
|
||||
|
||||
**Use Case**: You have on-premises or free models that should be accessible even when users exceed their budget limits.
|
||||
|
||||
**Solution** ✅: Set both `input_cost_per_token` and `output_cost_per_token` to `0` (explicitly) to bypass all budget checks for that model.
|
||||
|
||||
:::info
|
||||
|
||||
When a model is configured with zero cost, LiteLLM will automatically skip ALL budget checks (user, team, team member, end-user, organization, and global proxy budget) for requests to that model.
|
||||
|
||||
**Important**: Both costs must be **explicitly set to 0**. If costs are `null` or undefined, the model will be treated as having cost and budget checks will apply.
|
||||
|
||||
:::
|
||||
|
||||
### Configuration Example
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
# On-premises model - free to use
|
||||
- model_name: on-prem-llama
|
||||
litellm_params:
|
||||
model: ollama/llama3
|
||||
api_base: http://localhost:11434
|
||||
model_info:
|
||||
input_cost_per_token: 0 # 👈 Explicitly set to 0
|
||||
output_cost_per_token: 0 # 👈 Explicitly set to 0
|
||||
|
||||
# Paid cloud model - budget checks apply
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
# No model_info - uses default pricing from cost map
|
||||
```
|
||||
|
||||
### Behavior
|
||||
|
||||
With the above configuration:
|
||||
|
||||
- **User over budget** → Can still use `on-prem-llama` ✅, but blocked from `gpt-4` ❌
|
||||
- **Team over budget** → Can still use `on-prem-llama` ✅, but blocked from `gpt-4` ❌
|
||||
- **End-user over budget** → Can still use `on-prem-llama` ✅, but blocked from `gpt-4` ❌
|
||||
|
||||
This ensures your free/on-premises models remain accessible regardless of budget constraints, while paid models are still properly governed.
|
||||
|
||||
## Set 'base_model' for Cost Tracking (e.g. Azure deployments)
|
||||
|
||||
**Problem**: Azure returns `gpt-4` in the response when `azure/gpt-4-1106-preview` is used. This leads to inaccurate cost tracking
|
||||
|
|
|
|||
|
|
@ -22,19 +22,22 @@ Customer Usage enables you to track spend and usage for individual customers (en
|
|||
|
||||
## How to Track Spend
|
||||
|
||||
Track customer spend by including a `user` field in your API requests. The customer ID will be automatically tracked and associated with all spend from that request.
|
||||
Track customer spend by including a `user` field in your API requests or by passing a customer ID header. The customer ID will be automatically tracked and associated with all spend from that request.
|
||||
|
||||
### Example using cURL
|
||||
<Tabs>
|
||||
<TabItem value="body" label="Request Body" default>
|
||||
|
||||
### Using Request Body
|
||||
|
||||
Make a `/chat/completions` call with the `user` field containing your customer ID:
|
||||
|
||||
```bash showLineNumbers title="Track spend with customer ID"
|
||||
```bash showLineNumbers title="Track spend with customer ID in body"
|
||||
curl -X POST 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer sk-1234' \ # 👈 YOUR PROXY KEY
|
||||
--header 'Authorization: Bearer sk-1234' \
|
||||
--data '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"user": "customer-123", # 👈 CUSTOMER ID
|
||||
"user": "customer-123",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
|
|
@ -44,7 +47,49 @@ curl -X POST 'http://0.0.0.0:4000/chat/completions' \
|
|||
}'
|
||||
```
|
||||
|
||||
The customer ID (`customer-123`) will be automatically upserted into the database with the new spend. If the customer ID already exists, spend will be incremented.
|
||||
</TabItem>
|
||||
<TabItem value="header" label="Request Header">
|
||||
|
||||
### Using Request Headers
|
||||
|
||||
You can also pass the customer ID via HTTP headers. This is useful for tools that support custom headers but don't allow modifying the request body (like Claude Code with `ANTHROPIC_CUSTOM_HEADERS`).
|
||||
|
||||
LiteLLM automatically recognizes these standard headers (no configuration required):
|
||||
- `x-litellm-customer-id`
|
||||
- `x-litellm-end-user-id`
|
||||
|
||||
```bash showLineNumbers title="Track spend with customer ID in header"
|
||||
curl -X POST 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer sk-1234' \
|
||||
--header 'x-litellm-customer-id: customer-123' \
|
||||
--data '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What is the capital of France?"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
#### Using with Claude Code
|
||||
|
||||
Claude Code supports custom headers via the `ANTHROPIC_CUSTOM_HEADERS` environment variable. Set it to pass your customer ID:
|
||||
|
||||
```bash title="Configure Claude Code with customer tracking"
|
||||
export ANTHROPIC_BASE_URL="http://0.0.0.0:4000/v1/messages"
|
||||
export ANTHROPIC_API_KEY="sk-1234"
|
||||
export ANTHROPIC_CUSTOM_HEADERS="x-litellm-customer-id: my-customer-id"
|
||||
```
|
||||
|
||||
Now all requests from Claude Code will automatically track spend under `my-customer-id`.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
The customer ID will be automatically upserted into the database with the new spend. If the customer ID already exists, spend will be incremented.
|
||||
|
||||
### Example using OpenWebUI
|
||||
|
||||
|
|
|
|||
106
docs/my-website/docs/proxy/deleted_keys_teams.md
Normal file
106
docs/my-website/docs/proxy/deleted_keys_teams.md
Normal file
|
|
@ -0,0 +1,106 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Deleted Keys & Teams Audit Logs
|
||||
|
||||
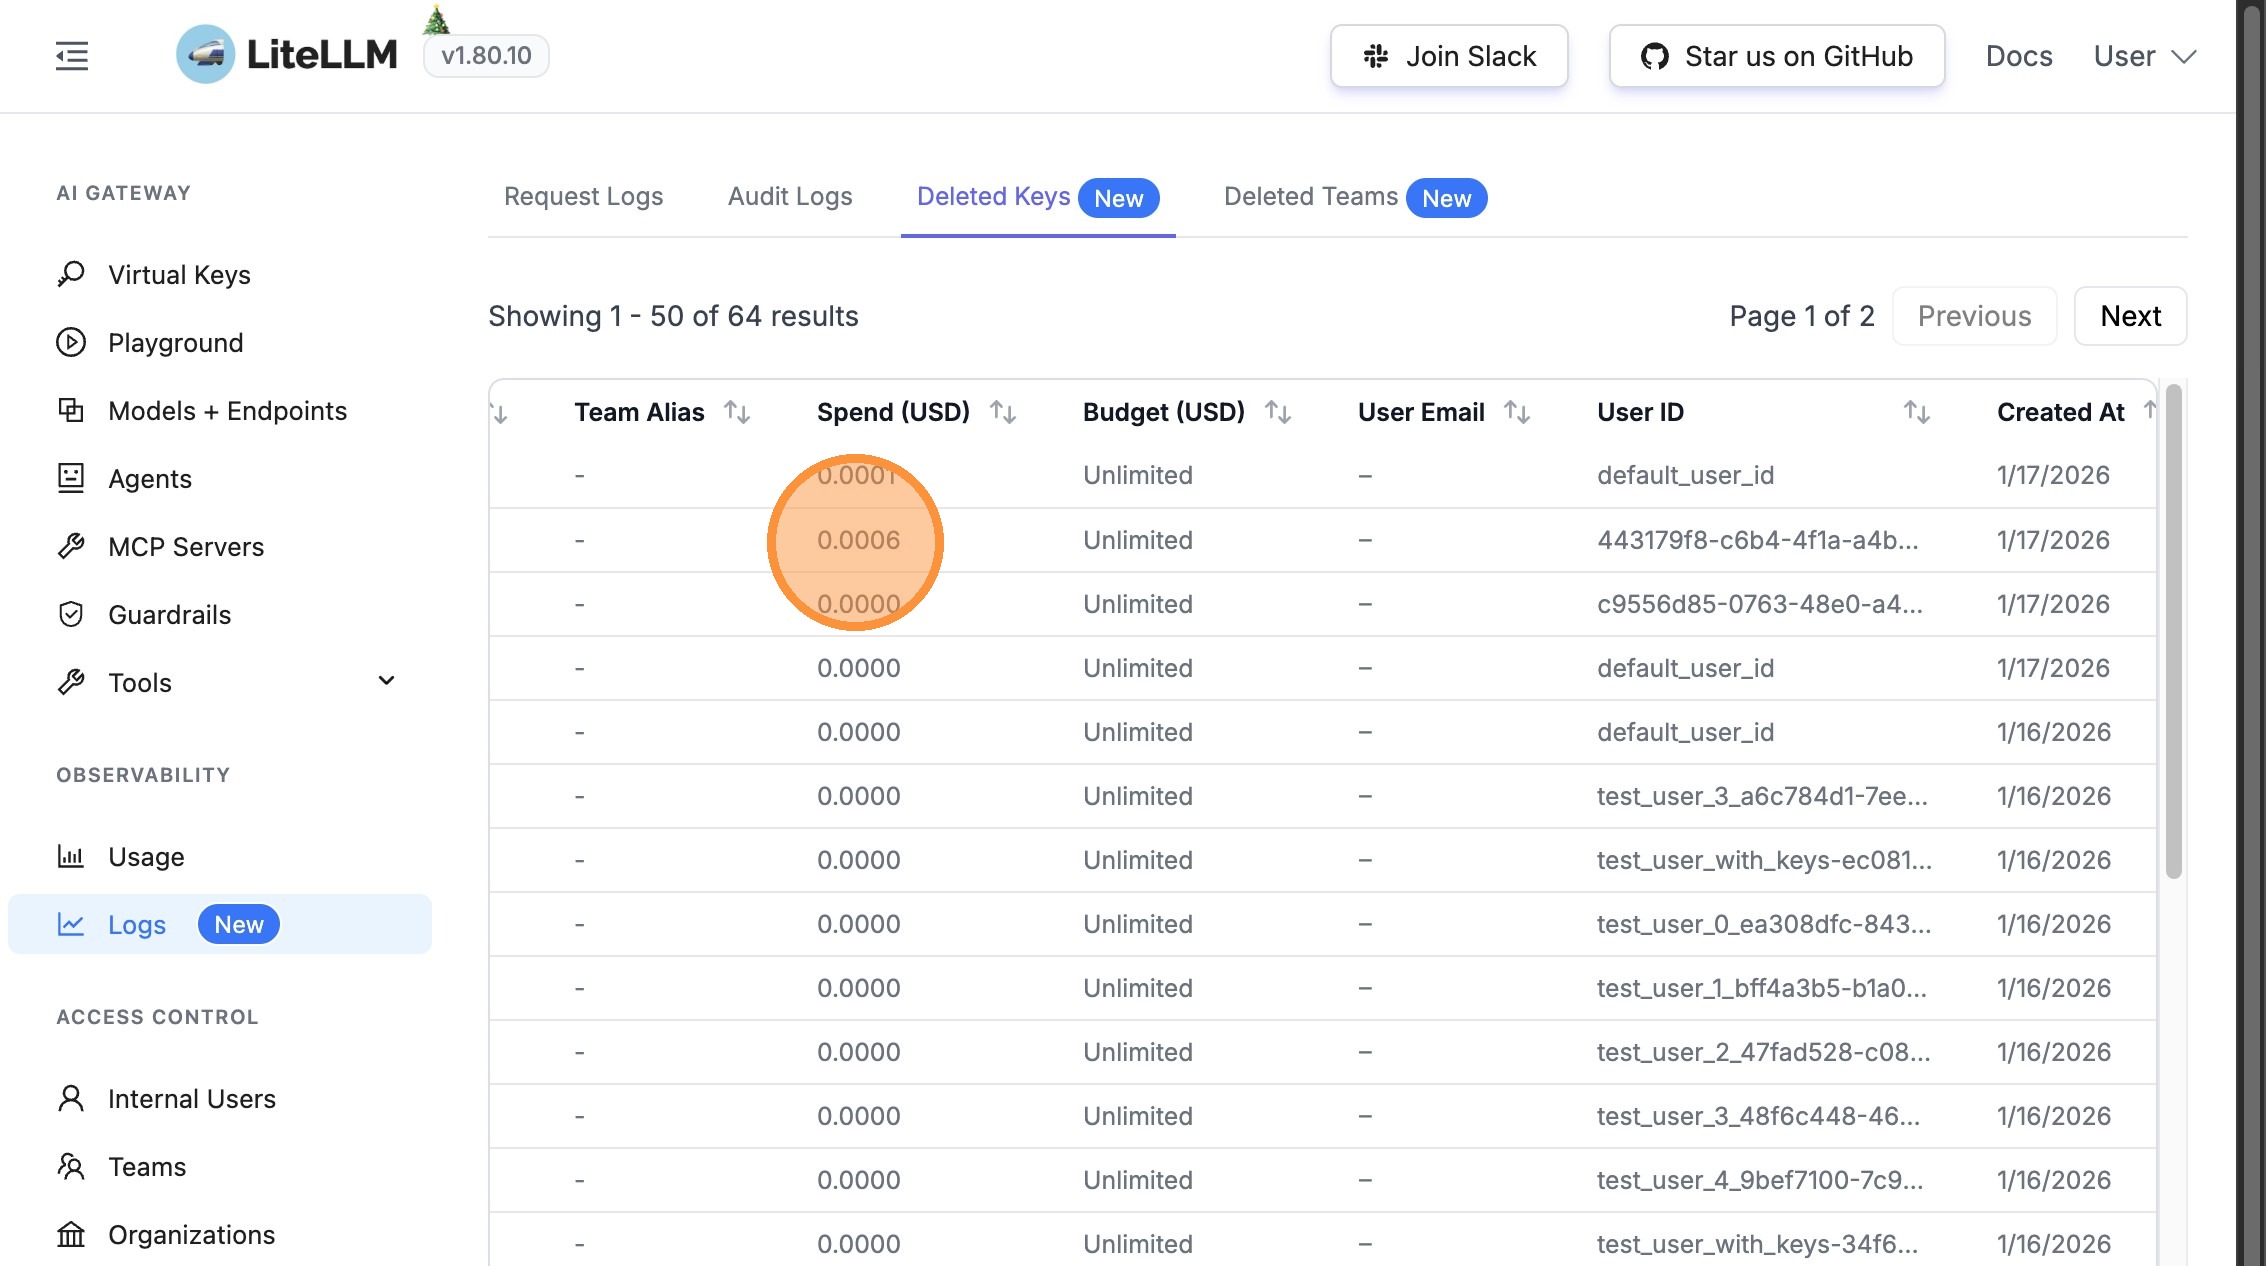
<Image img={require('../../img/ui_deleted_keys_table.png')} />
|
||||
|
||||
View deleted API keys and teams along with their spend and budget information at the time of deletion for auditing and compliance purposes.
|
||||
|
||||
## Overview
|
||||
|
||||
The Deleted Keys & Teams feature provides a comprehensive audit trail for deleted entities in your LiteLLM proxy. This feature was implemented to easily allow audits of which key or team was deleted along with the spend/budget at the time of deletion.
|
||||
|
||||
When a key or team is deleted, LiteLLM automatically captures:
|
||||
|
||||
- **Deletion timestamp** - When the entity was deleted
|
||||
- **Deleted by** - Who performed the deletion action
|
||||
- **Spend at deletion** - The total spend accumulated at the time of deletion
|
||||
- **Original budget** - The budget that was set for the entity before deletion
|
||||
- **Entity details** - Key or team identification information
|
||||
|
||||
This information is preserved even after deletion, allowing you to maintain accurate financial records and audit trails for compliance purposes.
|
||||
|
||||
## Viewing Deleted Keys
|
||||
|
||||
### Step 1: Navigate to API Keys Page
|
||||
|
||||
Navigate to the API Keys page in the LiteLLM UI:
|
||||
|
||||
```
|
||||
http://localhost:4000/ui/?login=success&page=api-keys
|
||||
```
|
||||
|
||||
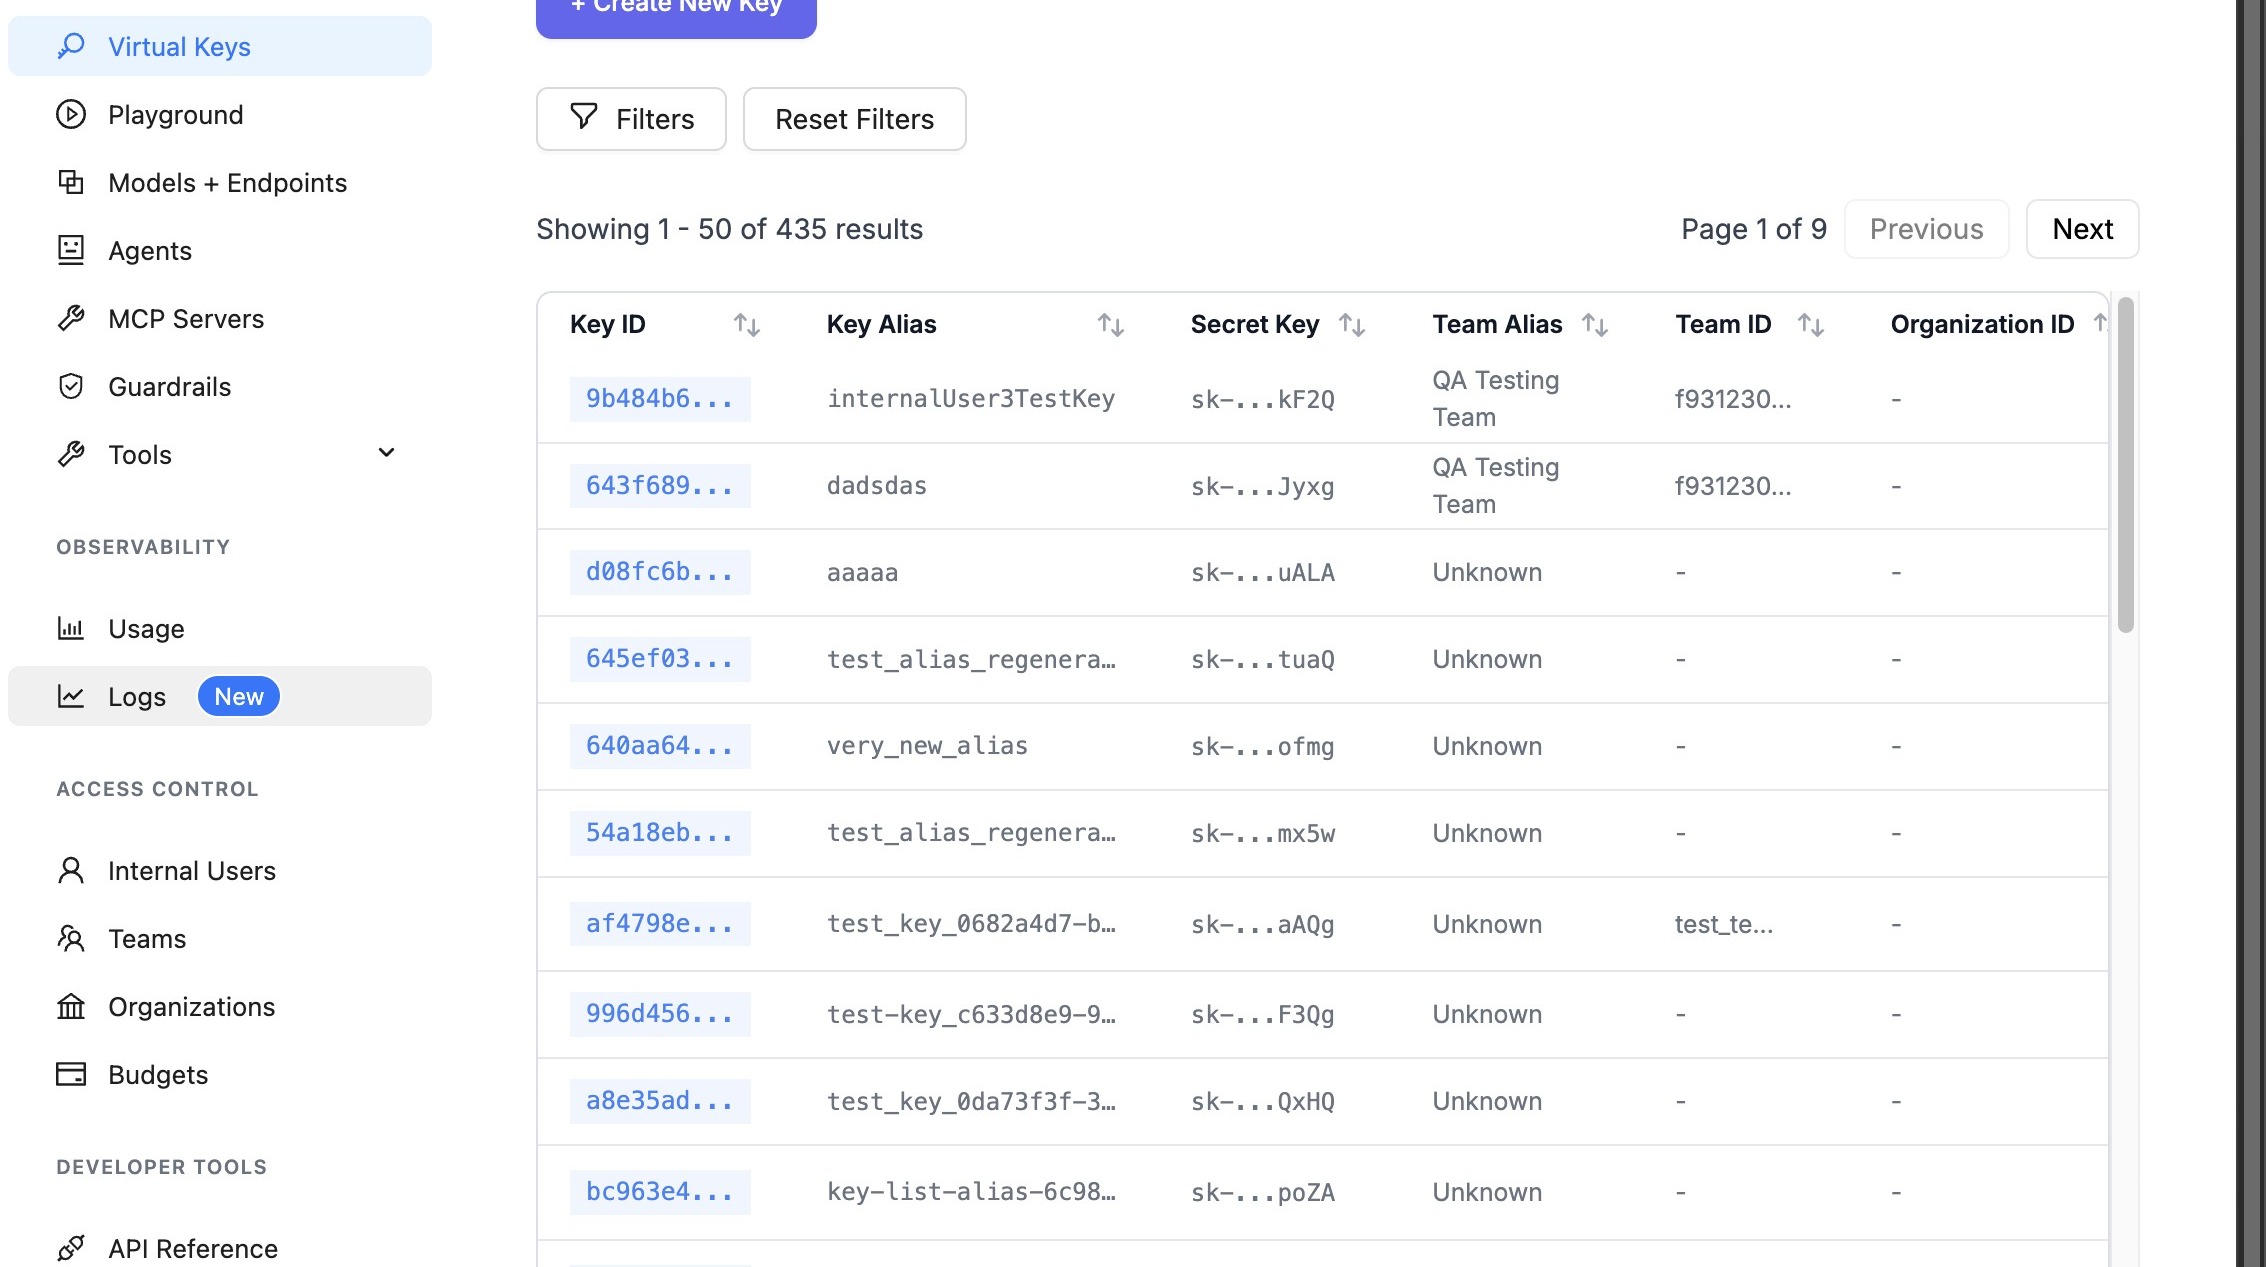
|
||||
|
||||
### Step 2: Access Logs Section
|
||||
|
||||
Click on the "Logs" menu item in the navigation.
|
||||
|
||||
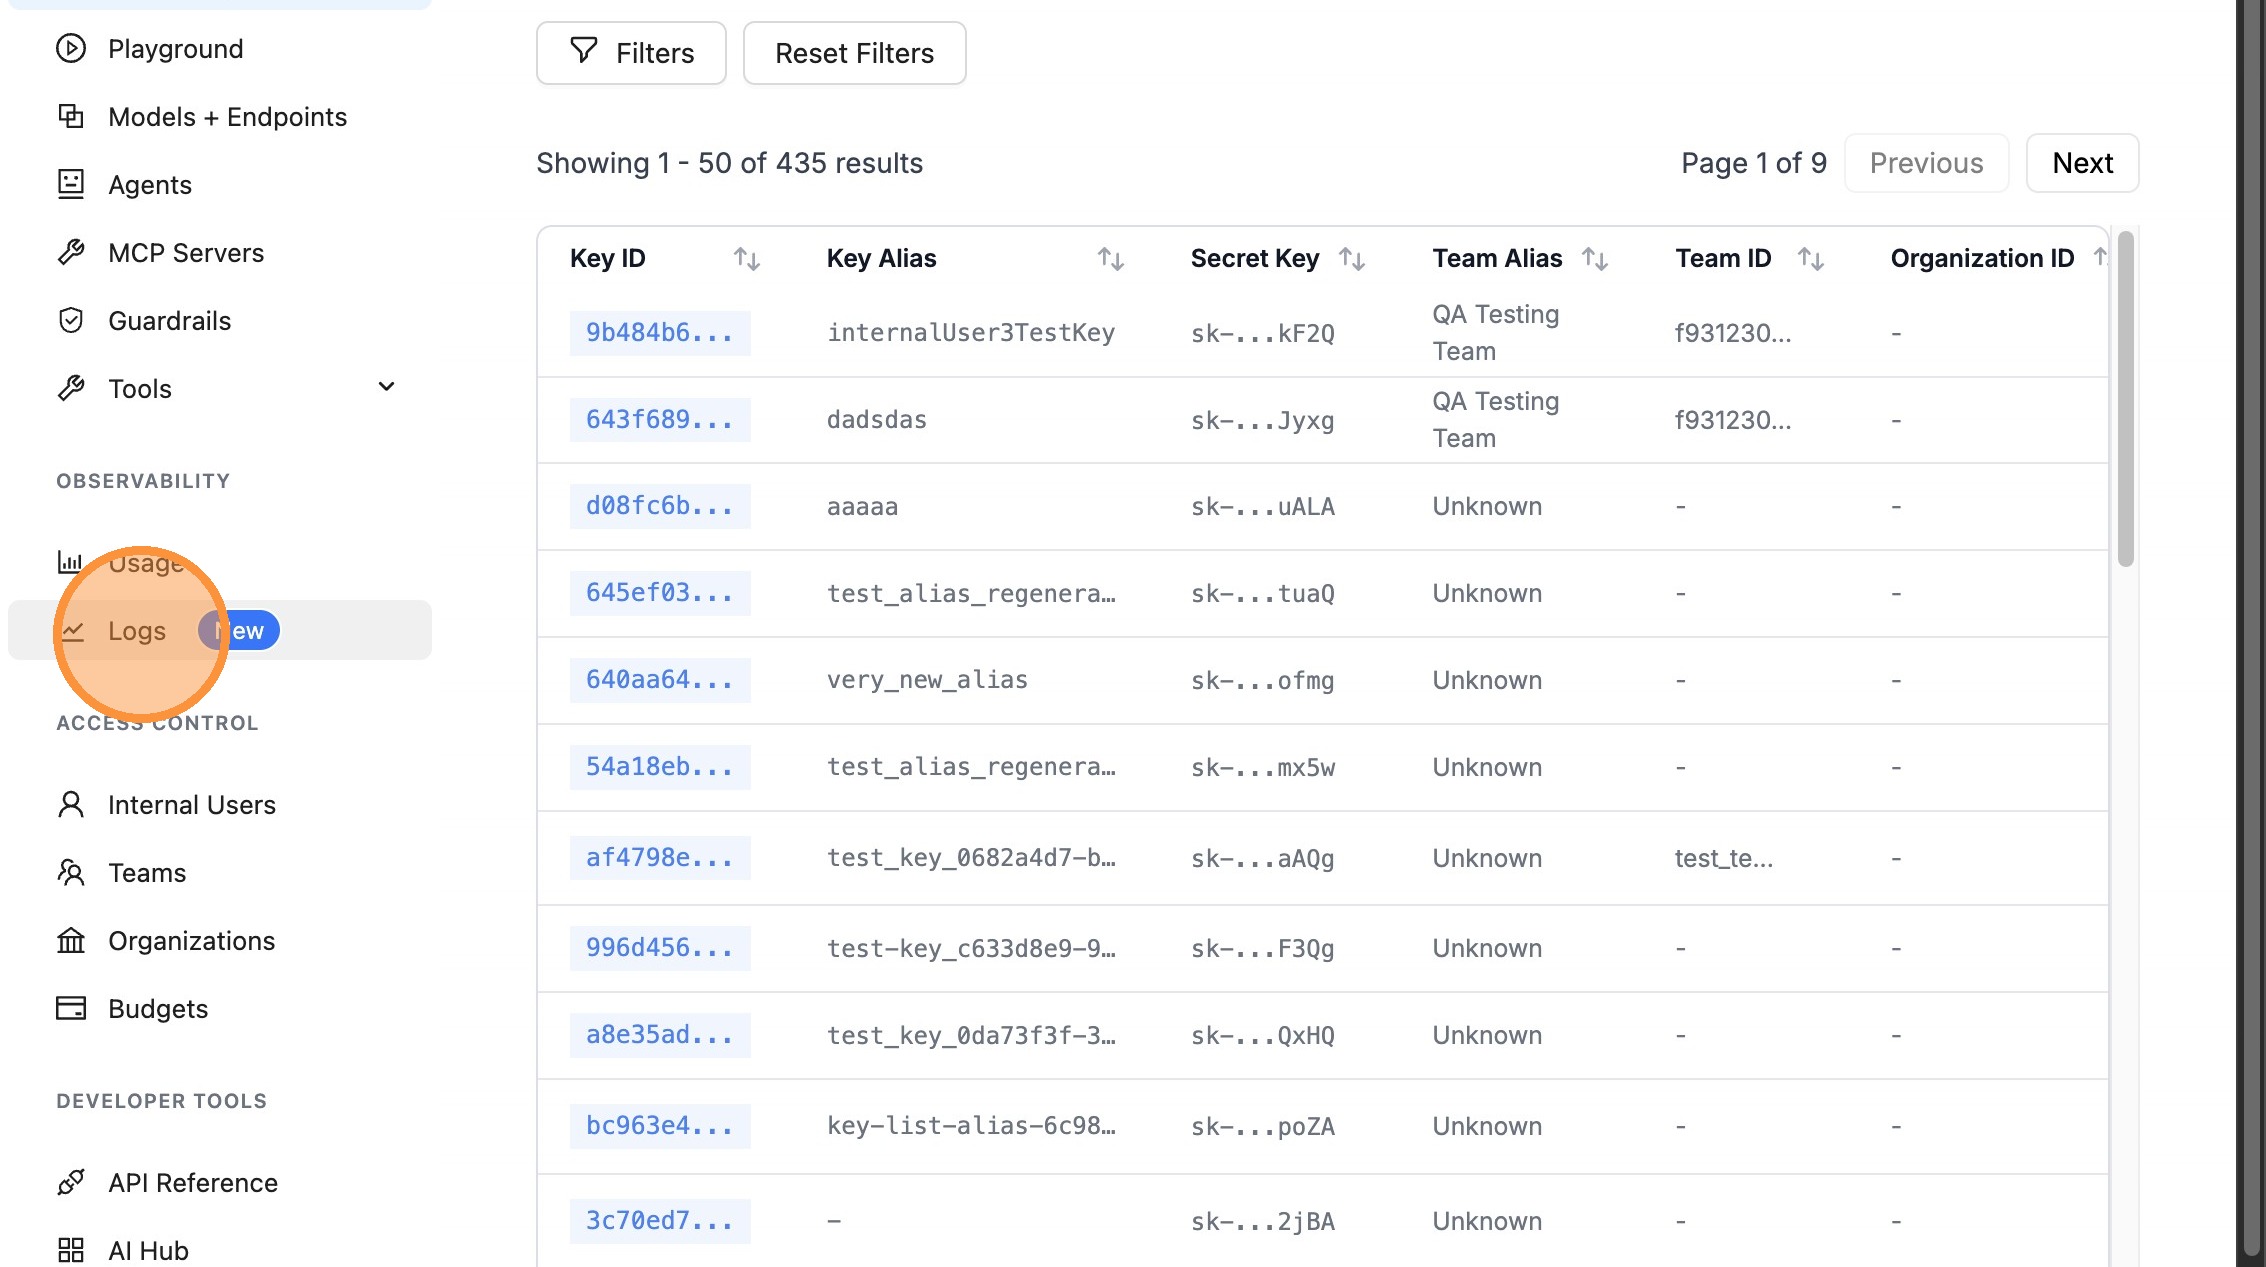
|
||||
|
||||
### Step 3: View Deleted Keys
|
||||
|
||||
Click on "Deleted Keys" to view the table of all deleted API keys.
|
||||
|
||||
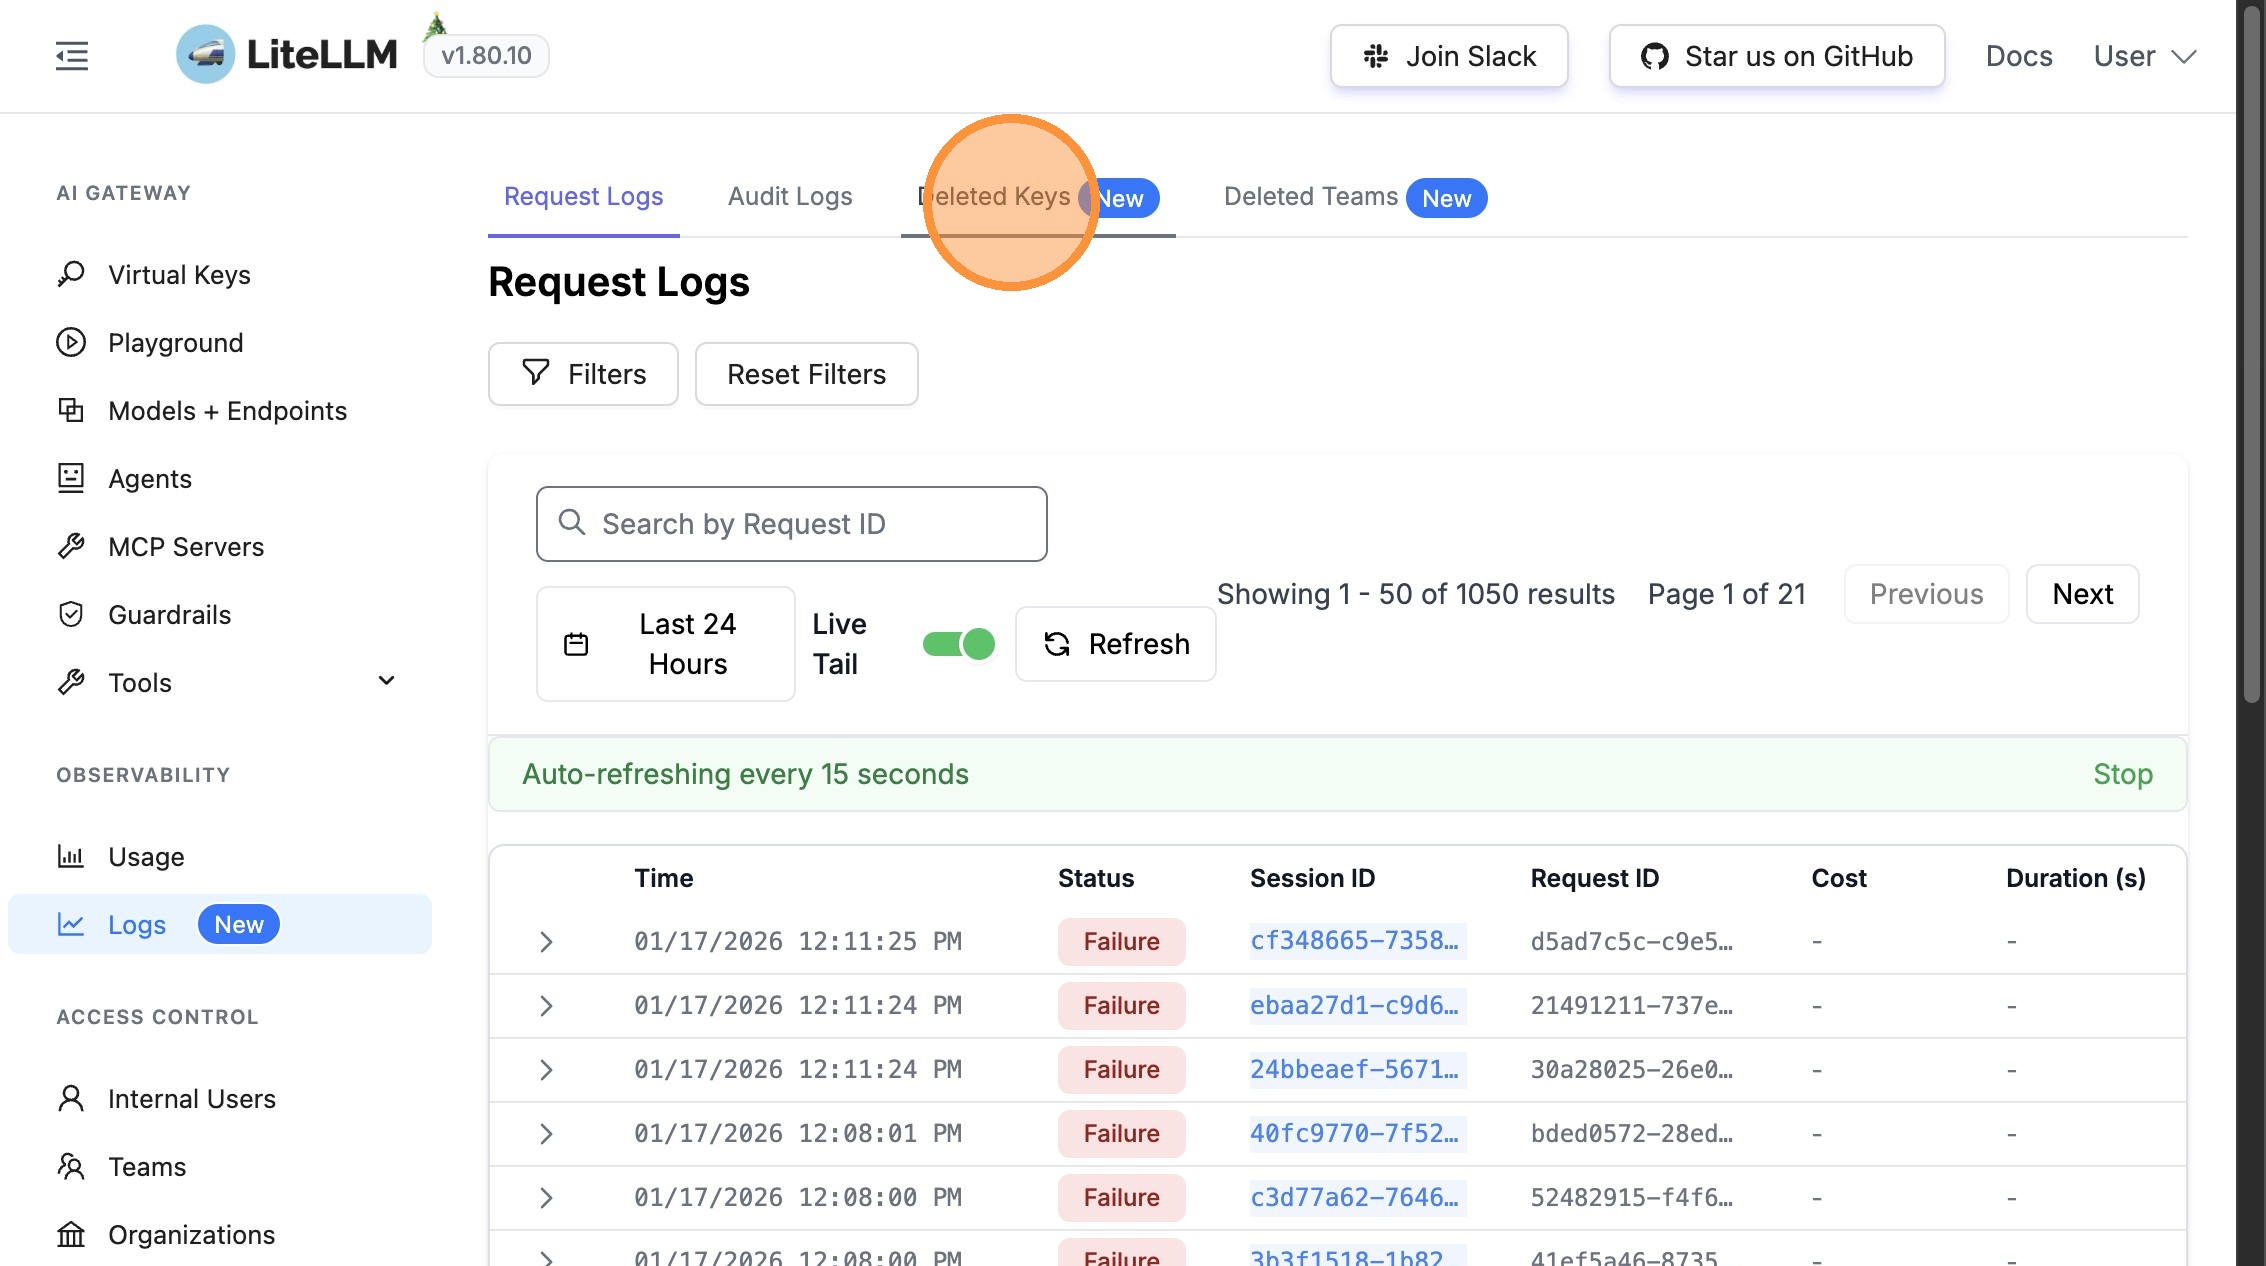
|
||||
|
||||
### Step 4: Review Deletion Information
|
||||
|
||||
The Deleted Keys table includes comprehensive information about each deleted key:
|
||||
|
||||
- **When** the key was deleted (timestamp)
|
||||
- **Who** deleted the key (user/admin information)
|
||||
- **Key identification** details
|
||||
|
||||
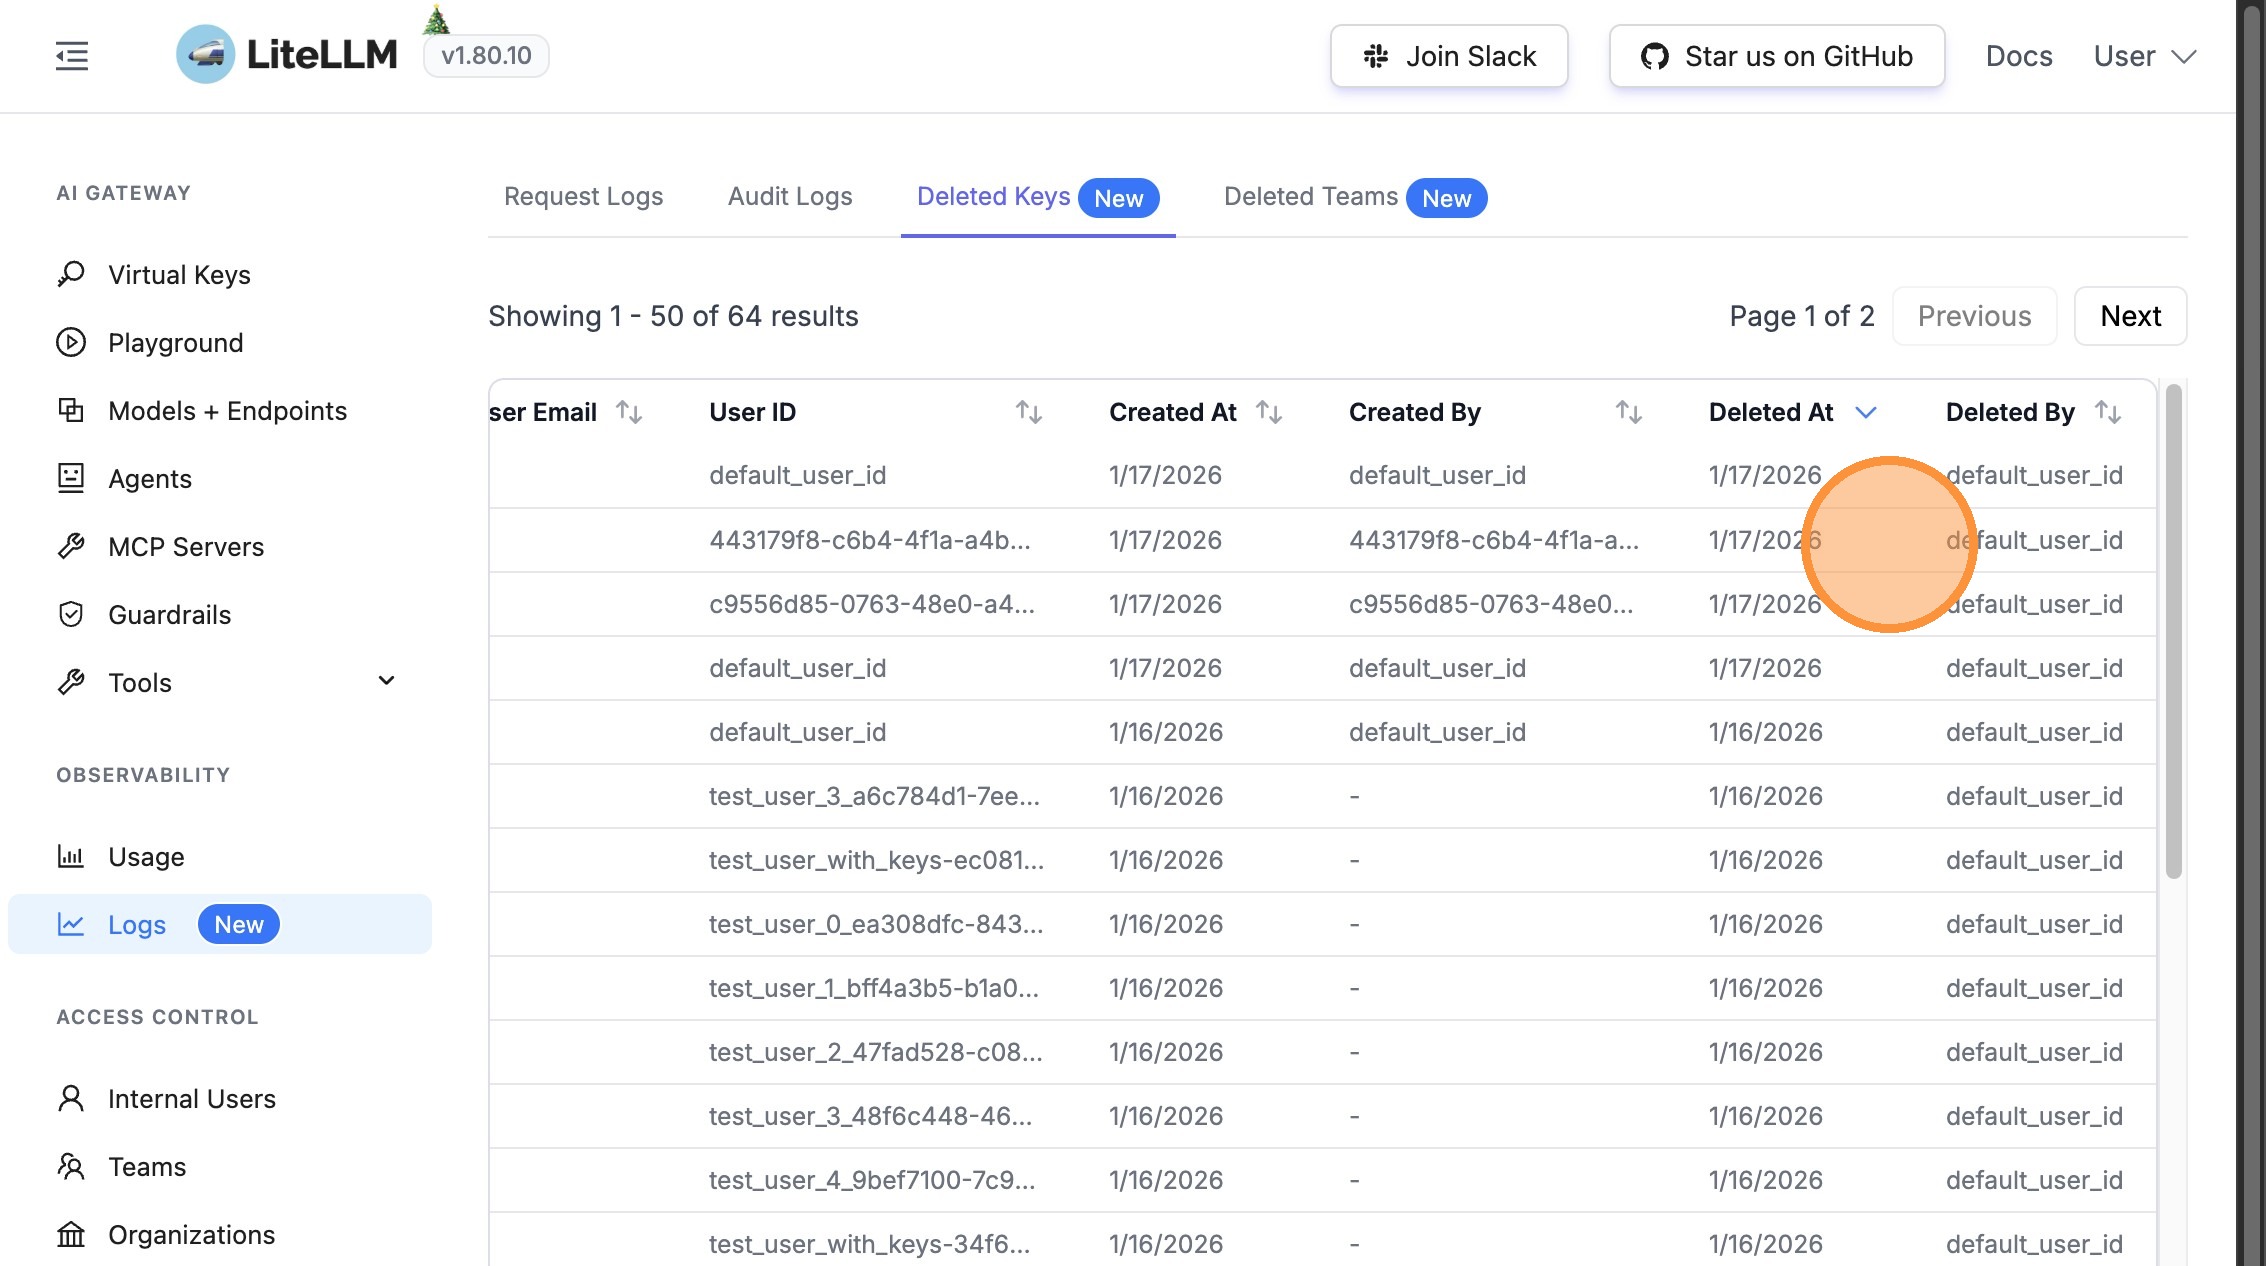
|
||||
|
||||
### Step 5: View Financial Information
|
||||
|
||||
The table also displays financial information captured at the time of deletion:
|
||||
|
||||
- **Spend at deletion** - Total spend accumulated when the key was deleted
|
||||
- **Original budget** - The budget limit that was set for the key
|
||||
|
||||
|
||||
|
||||
## Viewing Deleted Teams
|
||||
|
||||
### Step 1: Access Deleted Teams
|
||||
|
||||
From the Logs section, click on "Deleted Teams" to view all deleted teams.
|
||||
|
||||
|
||||
|
||||
### Step 2: Review Team Deletion Information
|
||||
|
||||
The Deleted Teams table provides detailed information about each deleted team:
|
||||
|
||||
- **When** the team was deleted (timestamp)
|
||||
- **Who** deleted the team (user/admin information)
|
||||
- **Team identification** details
|
||||
|
||||
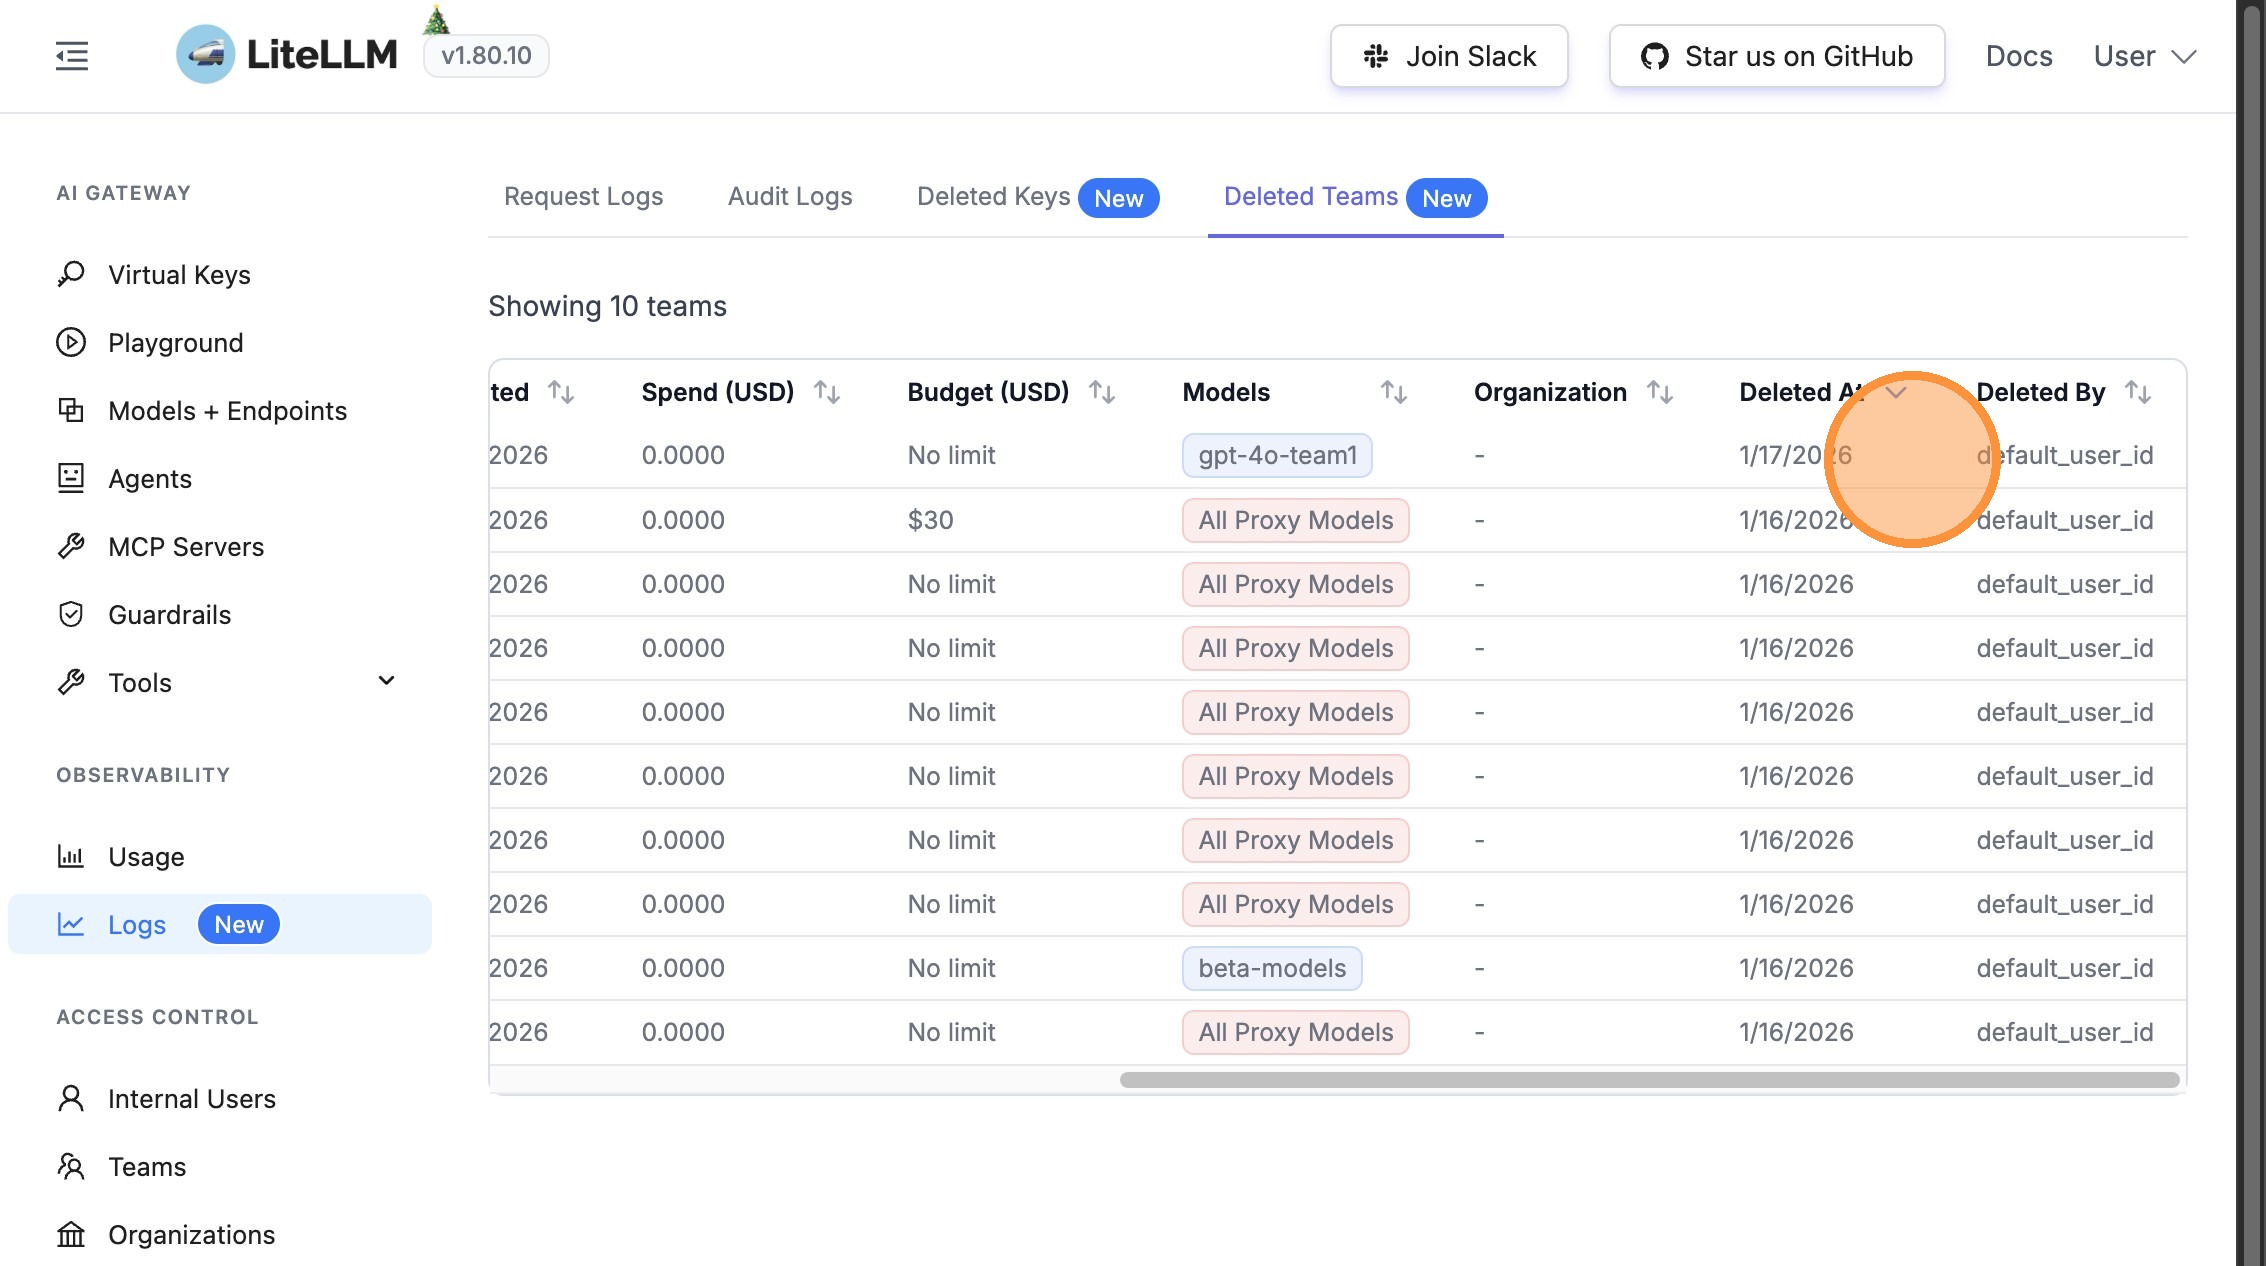
|
||||
|
||||
### Step 3: View Team Financial Information
|
||||
|
||||
Similar to deleted keys, the Deleted Teams table shows financial information:
|
||||
|
||||
- **Spend at deletion** - Total spend accumulated when the team was deleted
|
||||
- **Original budget** - The budget limit that was set for the team
|
||||
|
||||
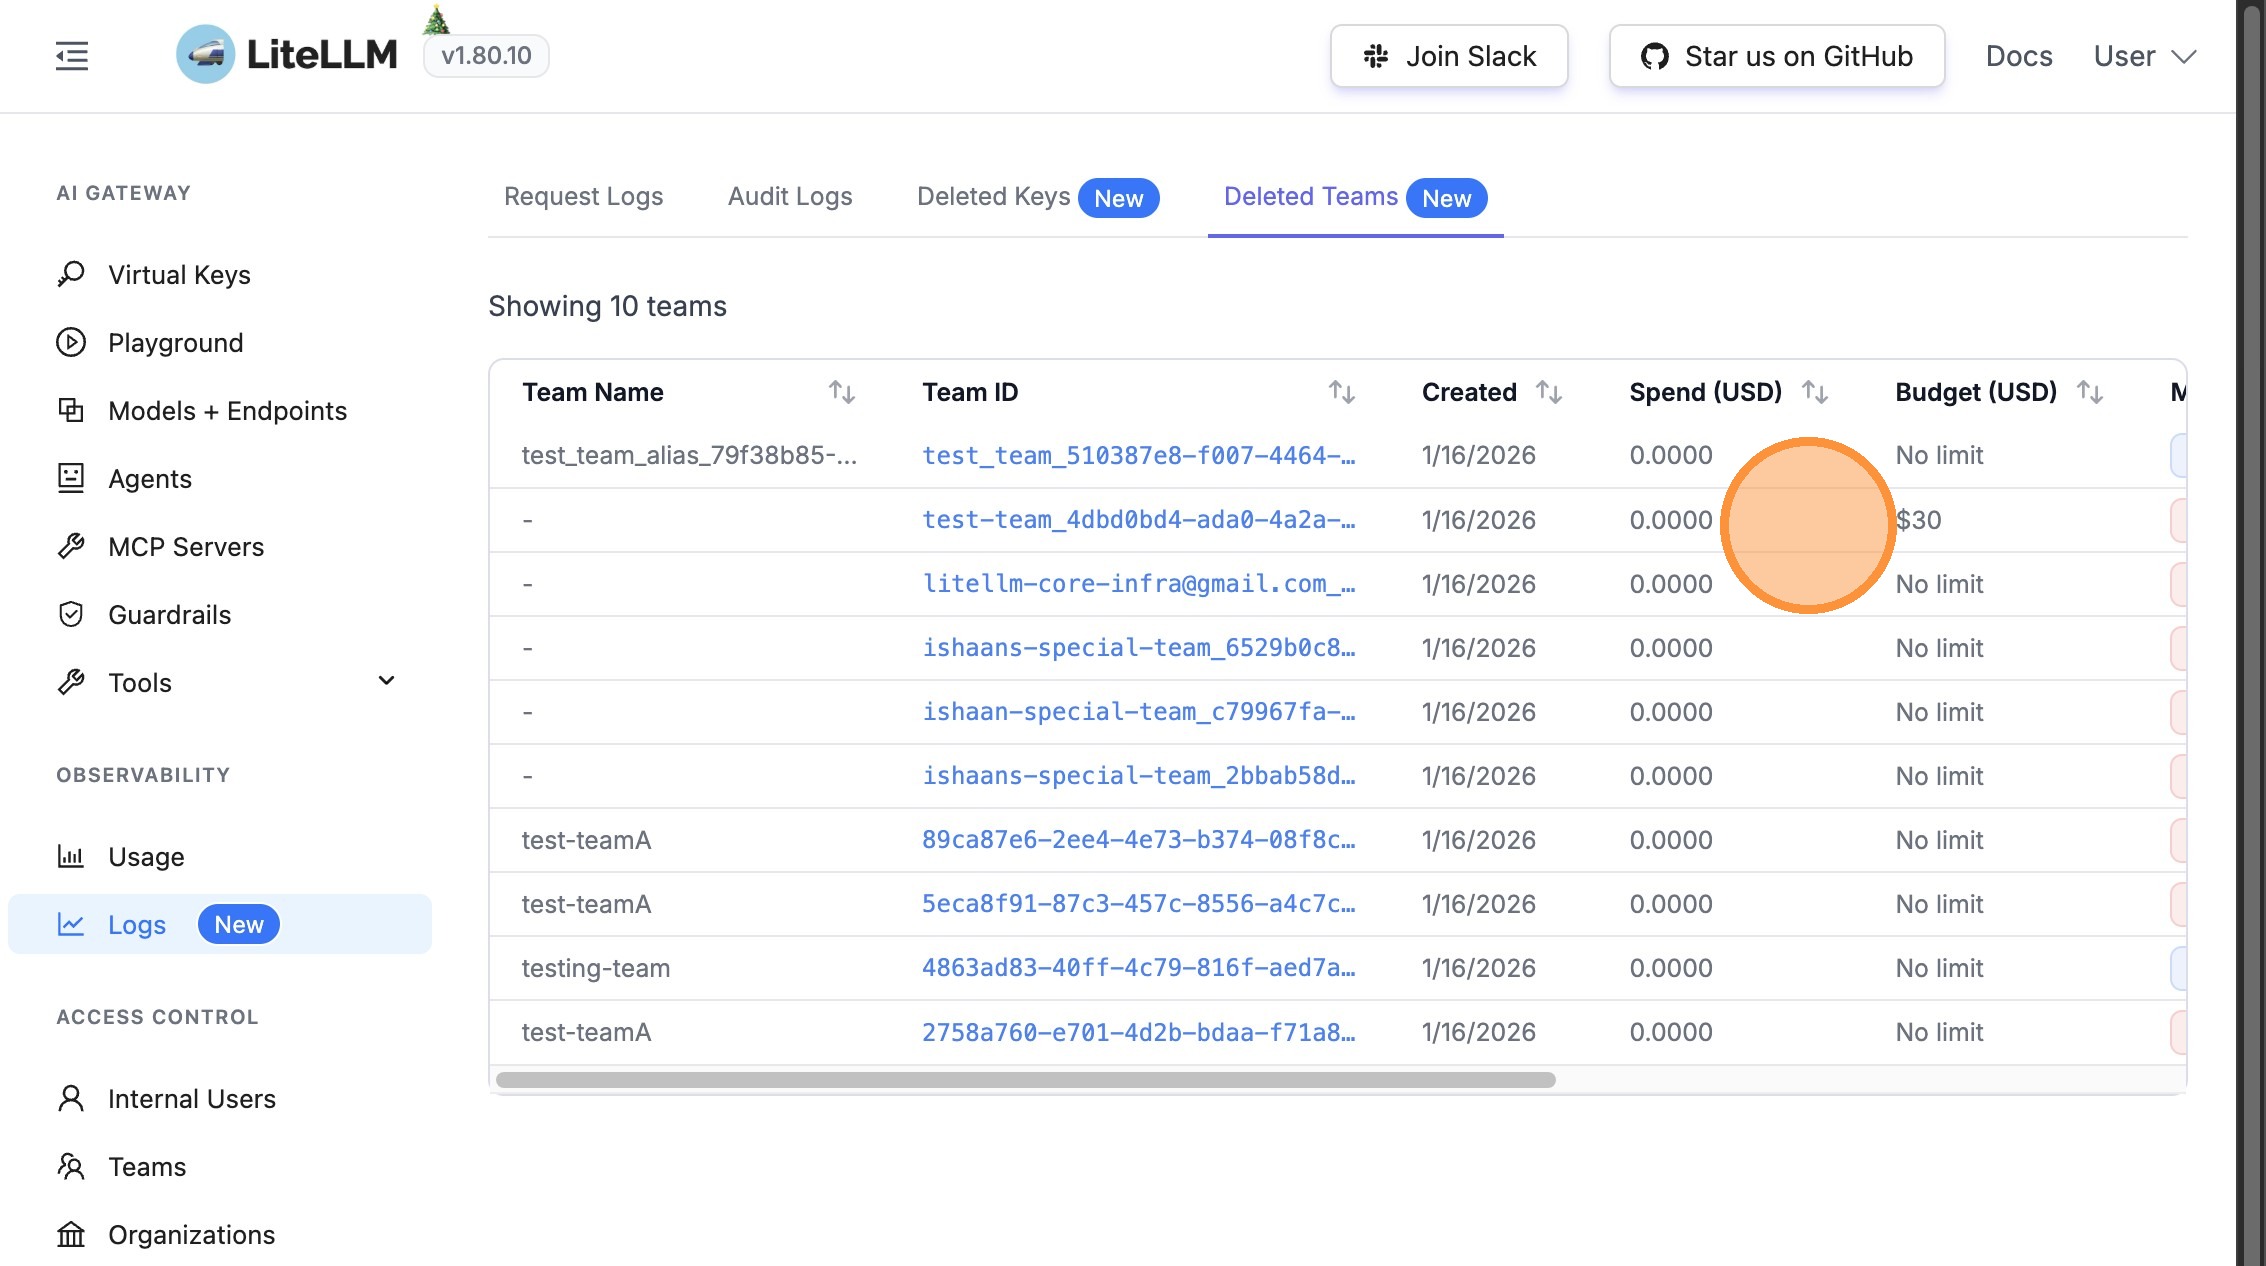
|
||||
|
||||
## Use Cases
|
||||
|
||||
This feature is particularly useful for:
|
||||
|
||||
- **Financial Auditing** - Track spend and budgets for deleted entities
|
||||
- **Compliance** - Maintain records of who deleted what and when
|
||||
- **Cost Analysis** - Understand spending patterns before deletion
|
||||
- **Accountability** - Identify which admin or user performed deletions
|
||||
- **Historical Records** - Preserve financial data even after entity deletion
|
||||
|
||||
## Related Features
|
||||
|
||||
- [Audit Logs](./multiple_admins.md) - View comprehensive audit logs for all entity changes
|
||||
- [UI Logs](./ui_logs.md) - View request logs and spend tracking
|
||||
267
docs/my-website/docs/proxy/fallback_management.md
Normal file
267
docs/my-website/docs/proxy/fallback_management.md
Normal file
|
|
@ -0,0 +1,267 @@
|
|||
# [New] Fallback Management Endpoints
|
||||
|
||||
Dedicated endpoints for managing model fallbacks separately from the general configuration.
|
||||
|
||||
## Overview
|
||||
|
||||
These endpoints allow you to configure, retrieve, and delete fallback models without modifying the entire proxy configuration. This provides a cleaner and safer way to manage fallbacks compared to using the `/config/update` endpoint.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
- Database storage must be enabled: Set `STORE_MODEL_IN_DB=True` in your environment
|
||||
- Models must exist in the router before configuring fallbacks
|
||||
|
||||
## Endpoints
|
||||
|
||||
### POST /fallback
|
||||
|
||||
Create or update fallbacks for a specific model.
|
||||
|
||||
**Request Body:**
|
||||
```json
|
||||
{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"fallback_models": ["gpt-4", "claude-3-haiku"],
|
||||
"fallback_type": "general"
|
||||
}
|
||||
```
|
||||
|
||||
**Parameters:**
|
||||
- `model` (string, required): The primary model name to configure fallbacks for
|
||||
- `fallback_models` (array of strings, required): List of fallback model names in priority order
|
||||
- `fallback_type` (string, optional): Type of fallback. Options:
|
||||
- `"general"` (default): Standard fallbacks for any error
|
||||
- `"context_window"`: Fallbacks for context window exceeded errors
|
||||
- `"content_policy"`: Fallbacks for content policy violations
|
||||
|
||||
**Response:**
|
||||
```json
|
||||
{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"fallback_models": ["gpt-4", "claude-3-haiku"],
|
||||
"fallback_type": "general",
|
||||
"message": "Fallback configuration created successfully"
|
||||
}
|
||||
```
|
||||
|
||||
**Example using cURL:**
|
||||
```bash
|
||||
curl -X POST "http://localhost:4000/fallback" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"fallback_models": ["gpt-4", "claude-3-haiku"],
|
||||
"fallback_type": "general"
|
||||
}'
|
||||
```
|
||||
|
||||
**Example using Python:**
|
||||
```python
|
||||
import requests
|
||||
|
||||
response = requests.post(
|
||||
"http://localhost:4000/fallback",
|
||||
headers={
|
||||
"Authorization": "Bearer sk-1234",
|
||||
"Content-Type": "application/json"
|
||||
},
|
||||
json={
|
||||
"model": "gpt-3.5-turbo",
|
||||
"fallback_models": ["gpt-4", "claude-3-haiku"],
|
||||
"fallback_type": "general"
|
||||
}
|
||||
)
|
||||
|
||||
print(response.json())
|
||||
```
|
||||
|
||||
### GET /fallback/\{model\}
|
||||
|
||||
Get fallback configuration for a specific model.
|
||||
|
||||
**Parameters:**
|
||||
- `model` (path parameter, required): The model name to get fallbacks for
|
||||
- `fallback_type` (query parameter, optional): Type of fallback to retrieve (default: "general")
|
||||
|
||||
**Response:**
|
||||
```json
|
||||
{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"fallback_models": ["gpt-4", "claude-3-haiku"],
|
||||
"fallback_type": "general"
|
||||
}
|
||||
```
|
||||
|
||||
**Example using cURL:**
|
||||
```bash
|
||||
curl -X GET "http://localhost:4000/fallback/gpt-3.5-turbo?fallback_type=general" \
|
||||
-H "Authorization: Bearer sk-1234"
|
||||
```
|
||||
|
||||
**Example using Python:**
|
||||
```python
|
||||
import requests
|
||||
|
||||
response = requests.get(
|
||||
"http://localhost:4000/fallback/gpt-3.5-turbo",
|
||||
headers={"Authorization": "Bearer sk-1234"},
|
||||
params={"fallback_type": "general"}
|
||||
)
|
||||
|
||||
print(response.json())
|
||||
```
|
||||
|
||||
### DELETE /fallback/\{model\}
|
||||
|
||||
Delete fallback configuration for a specific model.
|
||||
|
||||
**Parameters:**
|
||||
- `model` (path parameter, required): The model name to delete fallbacks for
|
||||
- `fallback_type` (query parameter, optional): Type of fallback to delete (default: "general")
|
||||
|
||||
**Response:**
|
||||
```json
|
||||
{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"fallback_type": "general",
|
||||
"message": "Fallback configuration deleted successfully"
|
||||
}
|
||||
```
|
||||
|
||||
**Example using cURL:**
|
||||
```bash
|
||||
curl -X DELETE "http://localhost:4000/fallback/gpt-3.5-turbo?fallback_type=general" \
|
||||
-H "Authorization: Bearer sk-1234"
|
||||
```
|
||||
|
||||
**Example using Python:**
|
||||
```python
|
||||
import requests
|
||||
|
||||
response = requests.delete(
|
||||
"http://localhost:4000/fallback/gpt-3.5-turbo",
|
||||
headers={"Authorization": "Bearer sk-1234"},
|
||||
params={"fallback_type": "general"}
|
||||
)
|
||||
|
||||
print(response.json())
|
||||
```
|
||||
|
||||
### Test fallback
|
||||
|
||||
```bash
|
||||
curl -X POST 'http://0.0.0.0:4000/chat/completions' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-d '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "ping"
|
||||
}
|
||||
],
|
||||
"mock_testing_fallbacks": true
|
||||
}
|
||||
'
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Validation
|
||||
|
||||
The endpoints perform the following validations:
|
||||
|
||||
1. **Model Existence**: Verifies that the primary model exists in the router
|
||||
2. **Fallback Model Existence**: Ensures all fallback models exist in the router
|
||||
3. **No Self-Fallback**: Prevents a model from being its own fallback
|
||||
4. **No Duplicates**: Ensures no duplicate models in the fallback list
|
||||
5. **Database Enabled**: Requires `STORE_MODEL_IN_DB=True` to be set
|
||||
|
||||
## Error Responses
|
||||
|
||||
### 400 Bad Request
|
||||
```json
|
||||
{
|
||||
"detail": {
|
||||
"error": "Invalid fallback models: ['non-existent-model']",
|
||||
"available_models": ["gpt-3.5-turbo", "gpt-4", "claude-3-haiku"]
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### 404 Not Found
|
||||
```json
|
||||
{
|
||||
"detail": {
|
||||
"error": "Model 'gpt-3.5-turbo' not found in router",
|
||||
"available_models": ["gpt-4", "claude-3-haiku"]
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### 500 Internal Server Error
|
||||
```json
|
||||
{
|
||||
"detail": {
|
||||
"error": "Router not initialized"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Fallback Types Explained
|
||||
|
||||
### General Fallbacks
|
||||
Used for any type of error that occurs during model invocation. This is the most common type of fallback.
|
||||
|
||||
**Use Case:** When a model is unavailable, rate-limited, or returns an error.
|
||||
|
||||
```json
|
||||
{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"fallback_models": ["gpt-4", "claude-3-haiku"],
|
||||
"fallback_type": "general"
|
||||
}
|
||||
```
|
||||
|
||||
### Context Window Fallbacks
|
||||
Specifically triggered when a context window exceeded error occurs.
|
||||
|
||||
**Use Case:** When the input is too long for the primary model, fallback to a model with a larger context window.
|
||||
|
||||
```json
|
||||
{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"fallback_models": ["gpt-4-32k", "claude-3-opus"],
|
||||
"fallback_type": "context_window"
|
||||
}
|
||||
```
|
||||
|
||||
### Content Policy Fallbacks
|
||||
Specifically triggered when content policy violations occur.
|
||||
|
||||
**Use Case:** When the primary model rejects content due to safety filters, fallback to a model with different content policies.
|
||||
|
||||
```json
|
||||
{
|
||||
"model": "gpt-4",
|
||||
"fallback_models": ["claude-3-haiku"],
|
||||
"fallback_type": "content_policy"
|
||||
}
|
||||
```
|
||||
|
||||
## Benefits Over /config/update
|
||||
|
||||
1. **Safety**: Only modifies fallback configuration, won't accidentally change other settings
|
||||
2. **Simplicity**: Focused API with clear validation messages
|
||||
3. **Granularity**: Manage fallbacks per model and per type
|
||||
4. **Validation**: Comprehensive checks ensure configuration is valid before applying
|
||||
5. **Clarity**: Clear error messages with available models listed
|
||||
|
||||
## Notes
|
||||
|
||||
- Fallbacks are triggered after the configured number of retries fails
|
||||
- Fallbacks are attempted in the order specified in `fallback_models`
|
||||
- The maximum number of fallbacks attempted is controlled by the router's `max_fallbacks` setting
|
||||
- Changes take effect immediately and are persisted to the database
|
||||
|
|
@ -206,6 +206,7 @@ Expected successful response:
|
|||
| `mode` | No | When to run the guardrail | `pre_call` |
|
||||
| `fallback_on_error` | No | Action when PANW API is unavailable: `"block"` (fail-closed, default) or `"allow"` (fail-open). Config errors always block. | `block` |
|
||||
| `timeout` | No | PANW API call timeout in seconds (1-60) | `10.0` |
|
||||
| `violation_message_template` | No | Custom template for error message when request is blocked. Supports `{guardrail_name}`, `{category}`, `{action_type}`, `{default_message}` placeholders. | - |
|
||||
|
||||
### Regional Endpoints
|
||||
|
||||
|
|
@ -449,6 +450,33 @@ LiteLLM does not alter or configure your PANW security profile. To change what c
|
|||
The guardrail is **fail-closed** by default - if the PANW API is unavailable, requests are blocked to ensure no unscanned content reaches your LLM. This provides maximum security.
|
||||
:::
|
||||
|
||||
### Custom Violation Messages
|
||||
|
||||
You can customize the error message returned to the user when a request is blocked by configuring the `violation_message_template` parameter. This is useful for providing user-friendly feedback instead of technical details.
|
||||
|
||||
```yaml
|
||||
guardrails:
|
||||
- guardrail_name: "panw-custom-message"
|
||||
litellm_params:
|
||||
guardrail: panw_prisma_airs
|
||||
api_key: os.environ/PANW_PRISMA_AIRS_API_KEY
|
||||
# Simple message
|
||||
violation_message_template: "Your request was blocked by our AI Security Policy."
|
||||
|
||||
- guardrail_name: "panw-detailed-message"
|
||||
litellm_params:
|
||||
guardrail: panw_prisma_airs
|
||||
api_key: os.environ/PANW_PRISMA_AIRS_API_KEY
|
||||
# Message with placeholders
|
||||
violation_message_template: "{action_type} blocked due to {category} violation. Please contact support."
|
||||
```
|
||||
|
||||
**Supported Placeholders:**
|
||||
- `{guardrail_name}`: Name of the guardrail (e.g. "panw-custom-message")
|
||||
- `{category}`: Violation category (e.g. "malicious", "injection", "dlp")
|
||||
- `{action_type}`: "Prompt" or "Response"
|
||||
- `{default_message}`: The original technical error message
|
||||
|
||||
### Fail-Open Configuration
|
||||
|
||||
By default, the PANW guardrail operates in **fail-closed** mode for maximum security. If the PANW API is unavailable (timeout, rate limit, network error), requests are blocked. You can configure **fail-open** mode for high-availability scenarios where service continuity is critical.
|
||||
|
|
|
|||
|
|
@ -30,6 +30,9 @@ general_settings:
|
|||
# Optional: set how frequently cleanup should run - default is daily
|
||||
maximum_spend_logs_retention_interval: "1d" # Run cleanup daily
|
||||
|
||||
# Optional: set exact time for cleanup (Cron syntax)
|
||||
maximum_spend_logs_cleanup_cron: "0 4 * * *" # Run at 04:00 AM daily
|
||||
|
||||
litellm_settings:
|
||||
cache: true
|
||||
cache_params:
|
||||
|
|
@ -51,6 +54,15 @@ How long logs should be kept before deletion. Supported formats:
|
|||
|
||||
How often the cleanup job should run. Uses the same format as above. If not set, cleanup will run every 24 hours if and only if `maximum_spend_logs_retention_period` is set.
|
||||
|
||||
#### `maximum_spend_logs_cleanup_cron` (optional)
|
||||
|
||||
Schedule the cleanup using standard cron syntax. This takes precedence over `maximum_spend_logs_retention_interval`.
|
||||
|
||||
Examples:
|
||||
- `"0 4 * * *"` – Run at 04:00 AM daily
|
||||
- `"0 0 * * 0"` – Run at midnight every Sunday
|
||||
- `"*/30 * * * *"` – Run every 30 minutes
|
||||
|
||||
## How it works
|
||||
|
||||
### Step 1. Lock Acquisition (Optional with Redis)
|
||||
|
|
|
|||
|
|
@ -1333,6 +1333,10 @@ router = Router(model_list: Optional[list] = None,
|
|||
cache_responses=True)
|
||||
```
|
||||
|
||||
:::info
|
||||
When configuring Redis caching in router settings, use `cache_kwargs` to pass additional Redis parameters, especially for non-string values that may fail when set via `REDIS_*` environment variables.
|
||||
:::
|
||||
|
||||
## Pre-Call Checks (Context Window, EU-Regions)
|
||||
|
||||
Enable pre-call checks to filter out:
|
||||
|
|
|
|||
|
|
@ -0,0 +1,99 @@
|
|||
# Claude Code - Granular Cost Tracking
|
||||
|
||||
Track Claude Code usage by customer or tags using LiteLLM proxy. This enables granular cost attribution for billing, budgeting, and analytics.
|
||||
|
||||
## How It Works
|
||||
|
||||
Claude Code supports custom headers via `ANTHROPIC_CUSTOM_HEADERS`. LiteLLM automatically tracks requests with specific headers for cost attribution.
|
||||
|
||||
## Tracking Options
|
||||
|
||||
Choose how you want to attribute costs:
|
||||
|
||||
| Track By | Header | Use Case |
|
||||
|----------|--------|----------|
|
||||
| Customer | `x-litellm-customer-id` | Bill customers, per-user budgets |
|
||||
| Tags | `x-litellm-tags` | Project tracking, cost centers, environments |
|
||||
|
||||
## Environment Variables
|
||||
|
||||
| Variable | Description | Example |
|
||||
|----------|-------------|---------|
|
||||
| `ANTHROPIC_BASE_URL` | LiteLLM proxy URL | `http://localhost:4000` |
|
||||
| `ANTHROPIC_API_KEY` | LiteLLM API key | `sk-1234` |
|
||||
| `ANTHROPIC_CUSTOM_HEADERS` | Custom headers (`header-name: value` format) | See examples below |
|
||||
|
||||
## Option 1: Track by Customer
|
||||
|
||||
Use this to attribute costs to specific customers or end-users.
|
||||
|
||||
```bash
|
||||
export ANTHROPIC_BASE_URL=http://localhost:4000
|
||||
export ANTHROPIC_API_KEY=sk-1234
|
||||
export ANTHROPIC_CUSTOM_HEADERS="x-litellm-customer-id: claude-ishaan-local"
|
||||
```
|
||||
|
||||
## Option 2: Track by Tags
|
||||
|
||||
Use this to attribute costs to projects, cost centers, or environments. Pass comma-separated tags.
|
||||
|
||||
```bash
|
||||
export ANTHROPIC_BASE_URL=http://localhost:4000
|
||||
export ANTHROPIC_API_KEY=sk-1234
|
||||
export ANTHROPIC_CUSTOM_HEADERS="x-litellm-tags: project:acme,env:prod,team:backend"
|
||||
```
|
||||
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Set Environment Variables
|
||||
|
||||
```bash
|
||||
export ANTHROPIC_BASE_URL=http://localhost:4000
|
||||
export ANTHROPIC_API_KEY=sk-1234
|
||||
export ANTHROPIC_CUSTOM_HEADERS="x-litellm-customer-id: claude-ishaan-local"
|
||||
```
|
||||
|
||||
### 2. Use Claude Code
|
||||
|
||||
```bash
|
||||
claude
|
||||
```
|
||||
|
||||
All requests will now be tracked under the customer ID `claude-ishaan-local`.
|
||||
|
||||
|
||||
|
||||
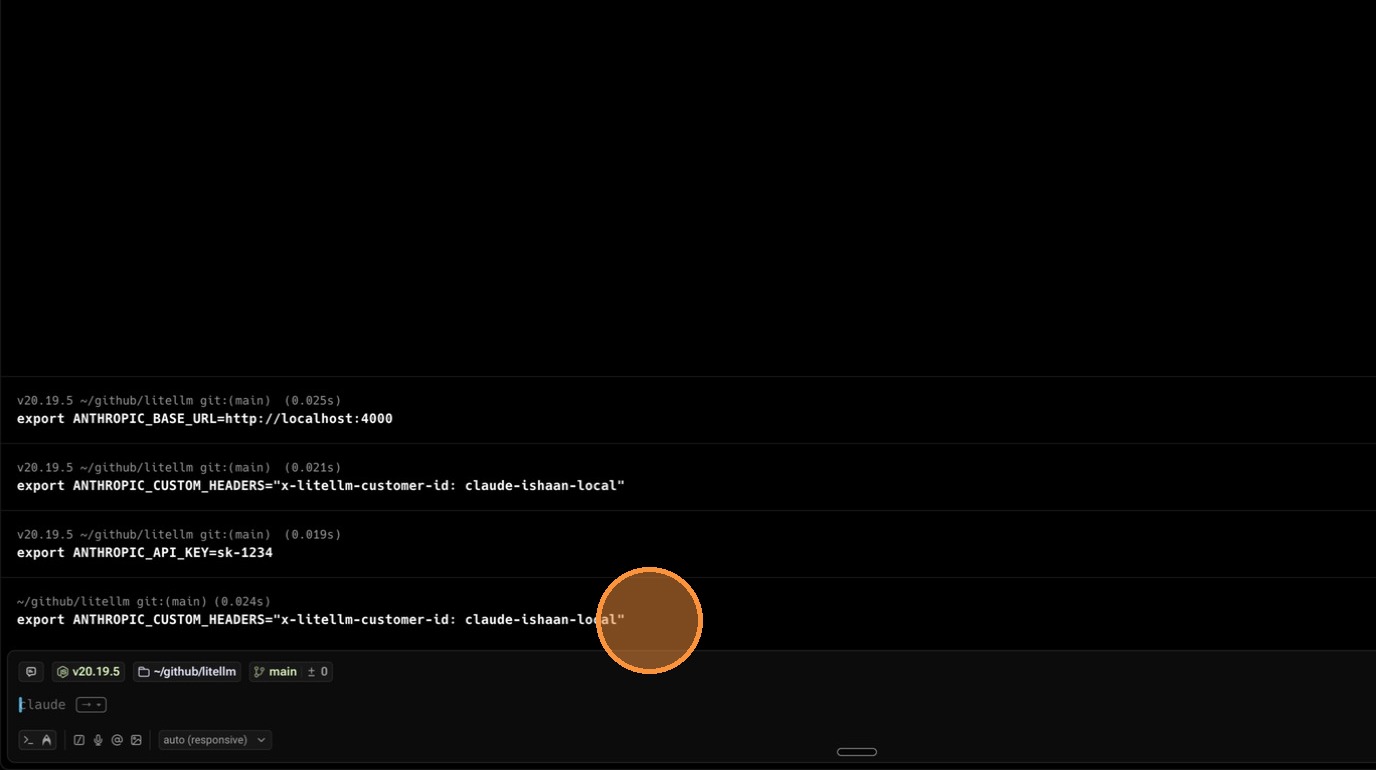
|
||||
|
||||
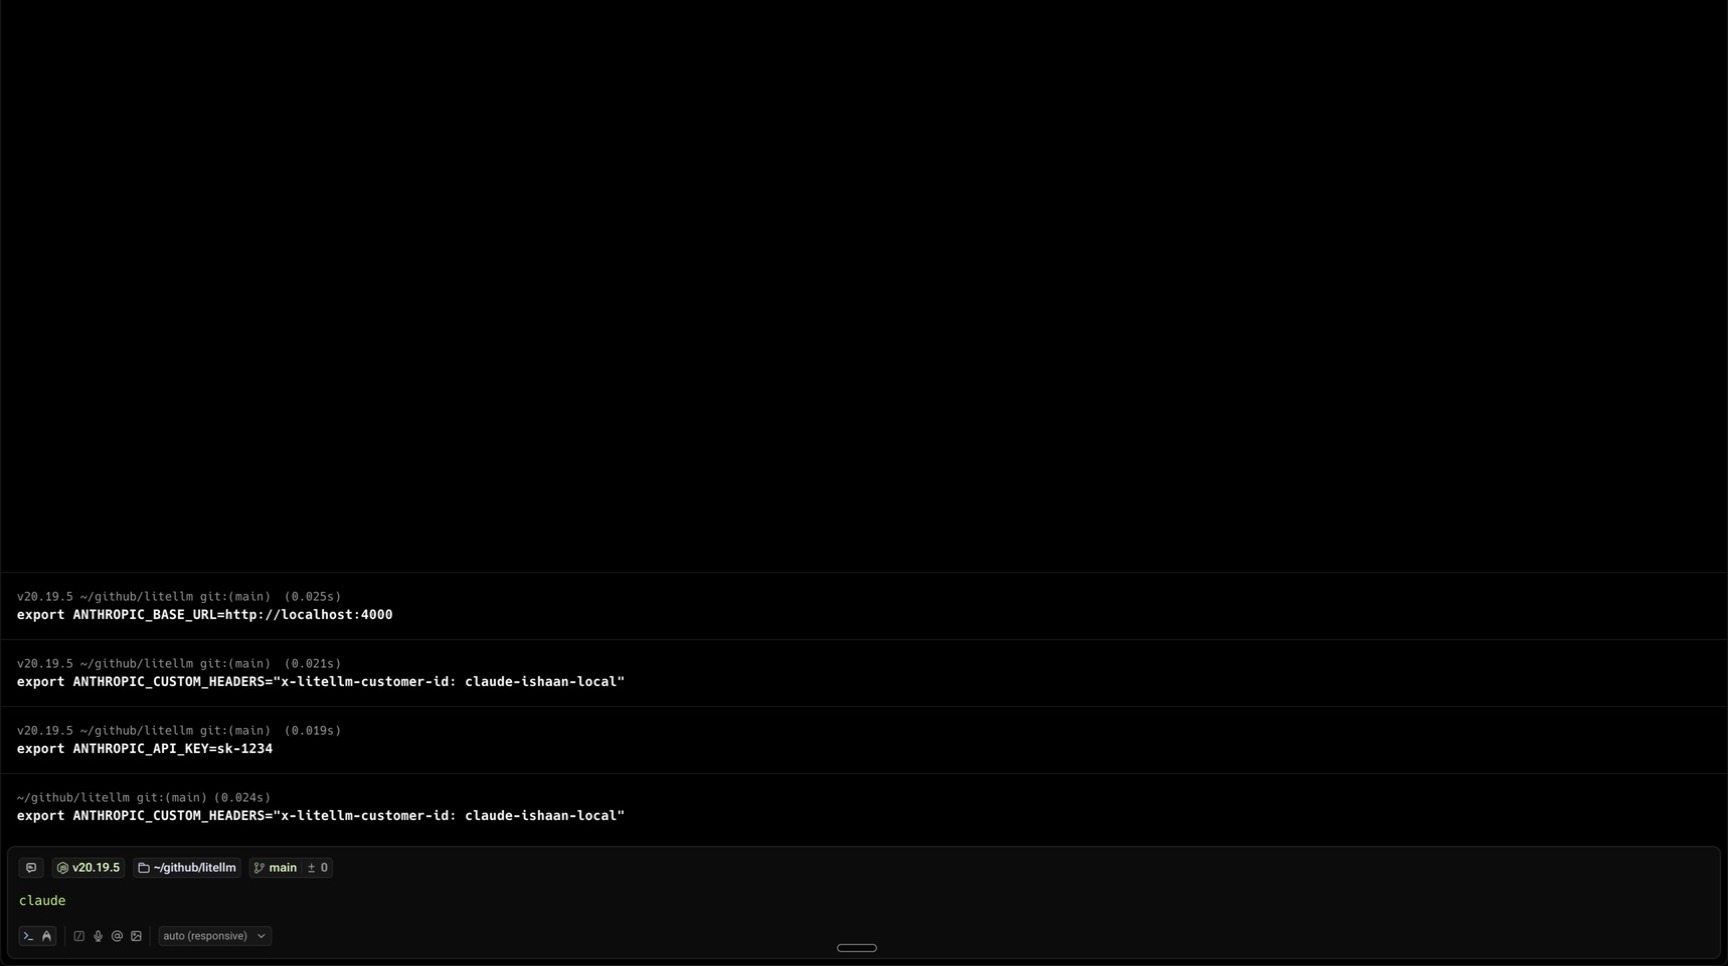
|
||||
|
||||
### 3. View Usage in LiteLLM UI
|
||||
|
||||
Navigate to the **Logs** tab in the LiteLLM UI.
|
||||
|
||||
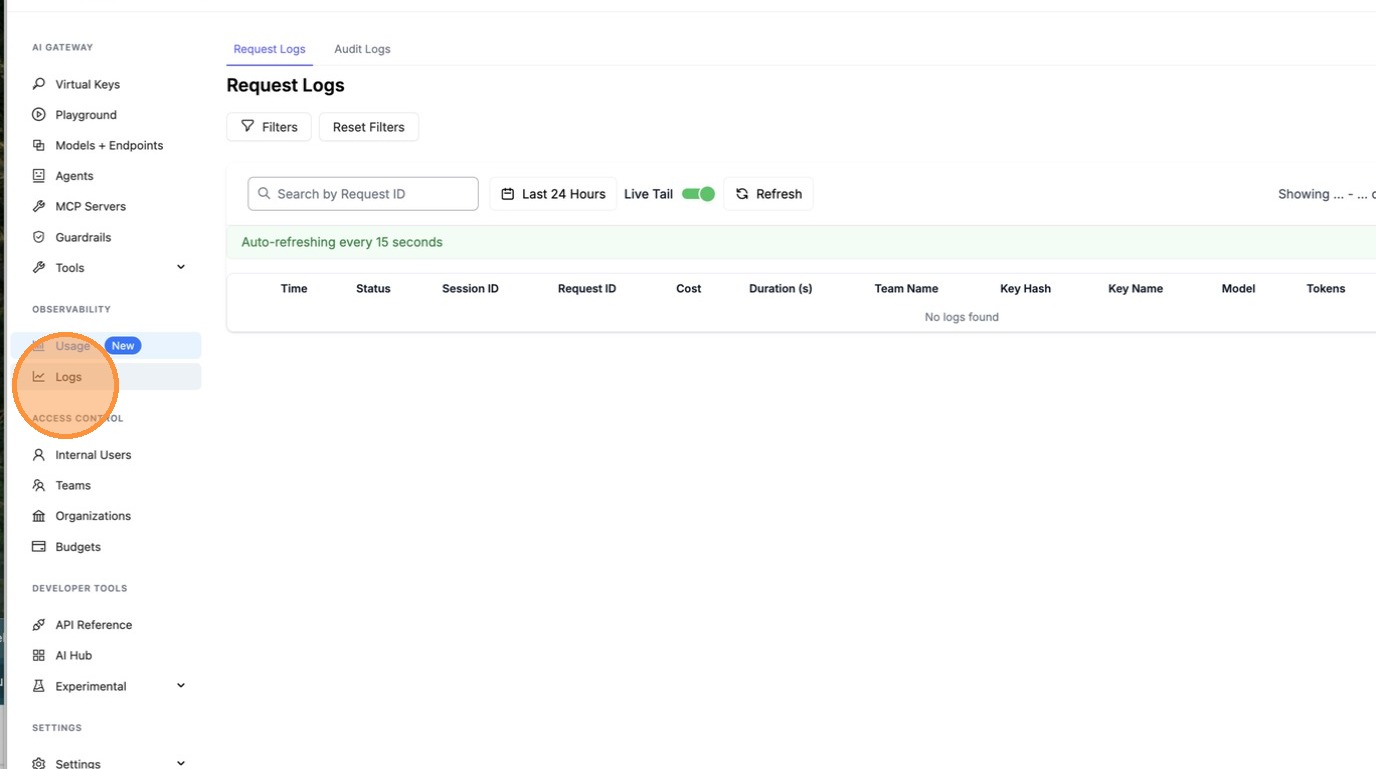
|
||||
|
||||
Click on a request to see details.
|
||||
|
||||
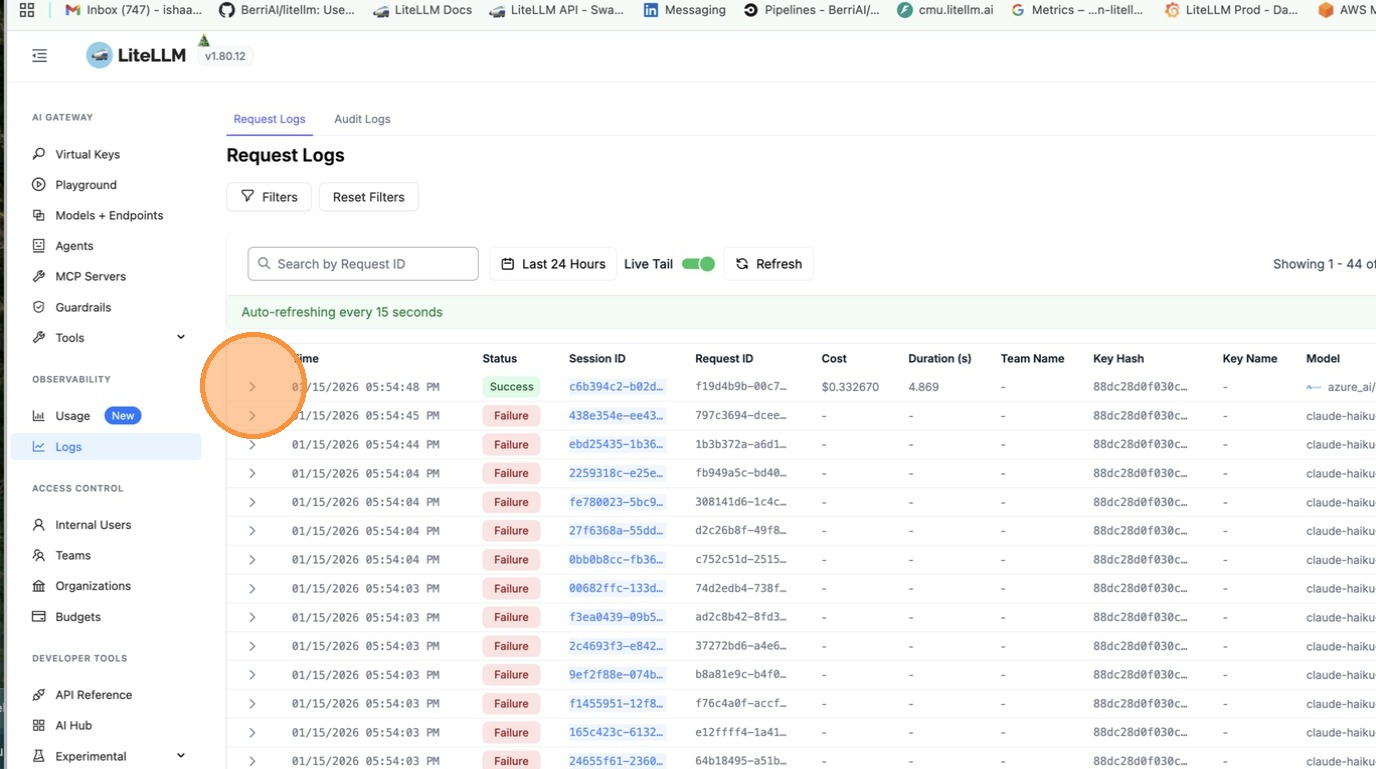
|
||||
|
||||
Filter by customer ID to see all requests for that customer.
|
||||
|
||||
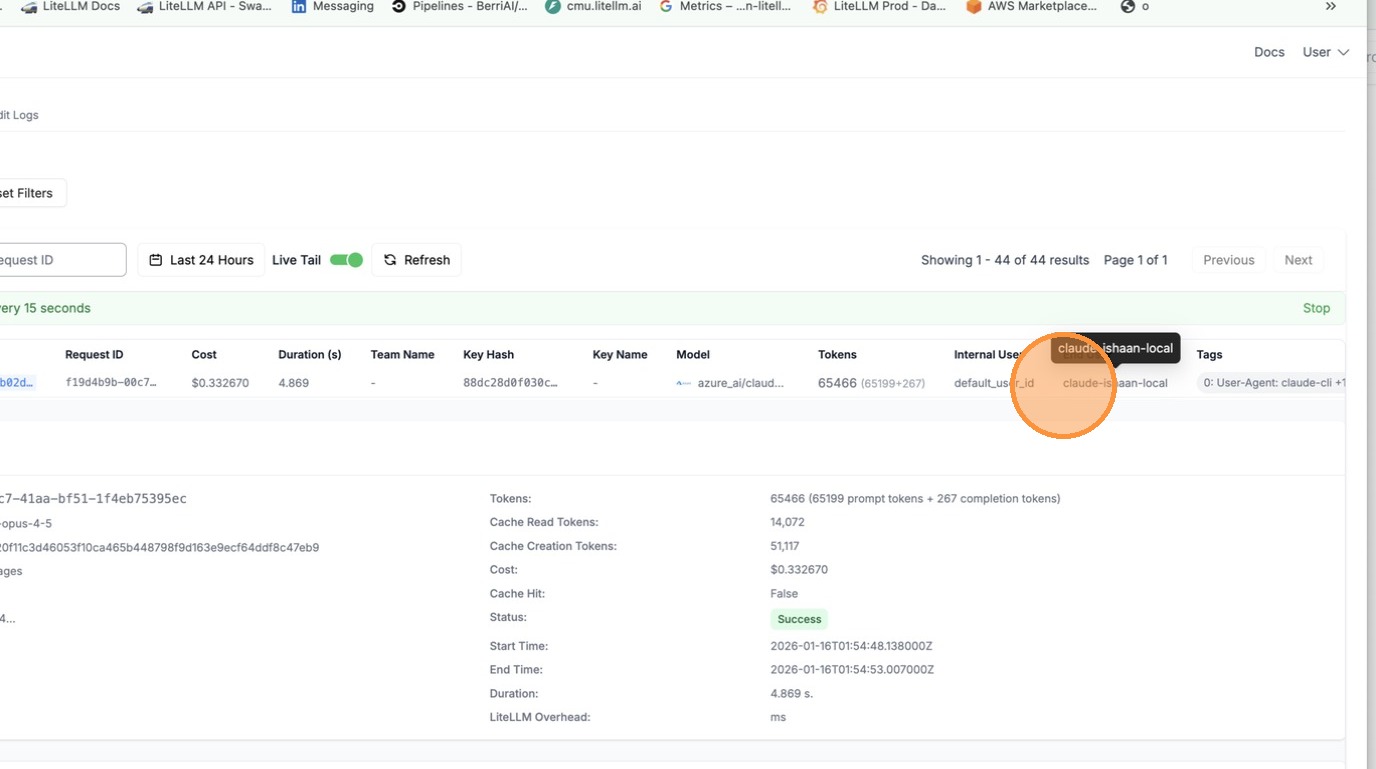
|
||||
|
||||
## Supported Headers
|
||||
|
||||
| Header | Description |
|
||||
|--------|-------------|
|
||||
| `x-litellm-customer-id` | Track by customer/end-user ID |
|
||||
| `x-litellm-end-user-id` | Alternative customer ID header |
|
||||
| `x-litellm-tags` | Comma-separated tags for cost attribution |
|
||||
|
||||
## Related
|
||||
|
||||
- [Claude Code Quickstart](./claude_responses_api.md)
|
||||
- [Customer Budgets](../proxy/customers.md)
|
||||
- [Tag Budgets](../proxy/tag_budgets.md)
|
||||
- [Track Usage for Coding Tools](./cost_tracking_coding.md)
|
||||
|
||||
192
docs/my-website/docs/tutorials/claude_code_websearch.md
Normal file
192
docs/my-website/docs/tutorials/claude_code_websearch.md
Normal file
|
|
@ -0,0 +1,192 @@
|
|||
# Claude Code - WebSearch Across All Providers
|
||||
|
||||
Enable Claude Code's web search tool to work with any provider (Bedrock, Azure, Vertex, etc.). LiteLLM automatically intercepts web search requests and executes them server-side.
|
||||
|
||||
## Proxy Configuration
|
||||
|
||||
Add WebSearch interception to your `litellm_config.yaml`:
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: bedrock-sonnet
|
||||
litellm_params:
|
||||
model: bedrock/us.anthropic.claude-sonnet-4-5-20250929-v1:0
|
||||
aws_region_name: us-east-1
|
||||
|
||||
# Enable WebSearch interception for providers
|
||||
litellm_settings:
|
||||
callbacks:
|
||||
- websearch_interception:
|
||||
enabled_providers:
|
||||
- bedrock
|
||||
- azure
|
||||
- vertex_ai
|
||||
search_tool_name: perplexity-search # Optional: specific search tool
|
||||
|
||||
# Configure search provider
|
||||
search_tools:
|
||||
- search_tool_name: perplexity-search
|
||||
litellm_params:
|
||||
search_provider: perplexity
|
||||
api_key: os.environ/PERPLEXITY_API_KEY
|
||||
```
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Configure LiteLLM Proxy
|
||||
|
||||
Create `config.yaml`:
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: bedrock-sonnet
|
||||
litellm_params:
|
||||
model: bedrock/us.anthropic.claude-sonnet-4-5-20250929-v1:0
|
||||
aws_region_name: us-east-1
|
||||
|
||||
litellm_settings:
|
||||
callbacks:
|
||||
- websearch_interception:
|
||||
enabled_providers: [bedrock]
|
||||
|
||||
search_tools:
|
||||
- search_tool_name: perplexity-search
|
||||
litellm_params:
|
||||
search_provider: perplexity
|
||||
api_key: os.environ/PERPLEXITY_API_KEY
|
||||
```
|
||||
|
||||
### 2. Start Proxy
|
||||
|
||||
```bash
|
||||
export PERPLEXITY_API_KEY=your-key
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
### 3. Use with Claude Code
|
||||
|
||||
```bash
|
||||
export ANTHROPIC_BASE_URL=http://localhost:4000
|
||||
export ANTHROPIC_API_KEY=sk-1234
|
||||
claude
|
||||
```
|
||||
|
||||
Now use web search in Claude Code - it works with any provider!
|
||||
|
||||
## How It Works
|
||||
|
||||
When Claude Code sends a web search request, LiteLLM:
|
||||
1. Intercepts the native `web_search` tool
|
||||
2. Converts it to LiteLLM's standard format
|
||||
3. Executes the search via Perplexity/Tavily
|
||||
4. Returns the final answer to Claude Code
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant CC as Claude Code
|
||||
participant LP as LiteLLM Proxy
|
||||
participant B as Bedrock/Azure/etc
|
||||
participant P as Perplexity/Tavily
|
||||
|
||||
CC->>LP: Request with web_search tool
|
||||
Note over LP: Convert native tool<br/>to LiteLLM format
|
||||
LP->>B: Request with converted tool
|
||||
B-->>LP: Response: tool_use
|
||||
Note over LP: Detect web search<br/>tool_use
|
||||
LP->>P: Execute search
|
||||
P-->>LP: Search results
|
||||
LP->>B: Follow-up with results
|
||||
B-->>LP: Final answer
|
||||
LP-->>CC: Final answer with search results
|
||||
```
|
||||
|
||||
**Result**: One API call from Claude Code → Complete answer with search results
|
||||
|
||||
## Supported Providers
|
||||
|
||||
| Provider | Native Web Search | With LiteLLM |
|
||||
|----------|-------------------|--------------|
|
||||
| **Anthropic** | ✅ Yes | ✅ Yes |
|
||||
| **Bedrock** | ❌ No | ✅ Yes |
|
||||
| **Azure** | ❌ No | ✅ Yes |
|
||||
| **Vertex AI** | ❌ No | ✅ Yes |
|
||||
| **Other Providers** | ❌ No | ✅ Yes |
|
||||
|
||||
## Search Providers
|
||||
|
||||
Configure which search provider to use. LiteLLM supports multiple search providers:
|
||||
|
||||
| Provider | Configuration |
|
||||
|----------|---------------|
|
||||
| **Perplexity** | `search_provider: perplexity` |
|
||||
| **Tavily** | `search_provider: tavily` |
|
||||
|
||||
See [all supported search providers](../search/index.md) for the complete list.
|
||||
|
||||
## Configuration Options
|
||||
|
||||
### WebSearch Interception Parameters
|
||||
|
||||
| Parameter | Type | Required | Description | Example |
|
||||
|-----------|------|----------|-------------|---------|
|
||||
| `enabled_providers` | List[String] | Yes | List of providers to enable web search interception for | `[bedrock, azure, vertex_ai]` |
|
||||
| `search_tool_name` | String | No | Specific search tool from `search_tools` config. If not set, uses first available search tool. | `perplexity-search` |
|
||||
|
||||
### Supported Provider Values
|
||||
|
||||
Use these values in `enabled_providers`:
|
||||
|
||||
| Provider | Value | Description |
|
||||
|----------|-------|-------------|
|
||||
| AWS Bedrock | `bedrock` | Amazon Bedrock Claude models |
|
||||
| Azure OpenAI | `azure` | Azure-hosted models |
|
||||
| Google Vertex AI | `vertex_ai` | Google Cloud Vertex AI |
|
||||
| Any Other | Provider name | Any LiteLLM-supported provider |
|
||||
|
||||
### Complete Configuration Example
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: bedrock-sonnet
|
||||
litellm_params:
|
||||
model: bedrock/us.anthropic.claude-sonnet-4-5-20250929-v1:0
|
||||
aws_region_name: us-east-1
|
||||
|
||||
- model_name: azure-gpt4
|
||||
litellm_params:
|
||||
model: azure/gpt-4
|
||||
api_base: https://my-azure.openai.azure.com
|
||||
api_key: os.environ/AZURE_API_KEY
|
||||
|
||||
litellm_settings:
|
||||
callbacks:
|
||||
- websearch_interception:
|
||||
enabled_providers:
|
||||
- bedrock # Enable for AWS Bedrock
|
||||
- azure # Enable for Azure OpenAI
|
||||
- vertex_ai # Enable for Google Vertex
|
||||
search_tool_name: perplexity-search # Optional: use specific search tool
|
||||
|
||||
# Configure search tools
|
||||
search_tools:
|
||||
- search_tool_name: perplexity-search
|
||||
litellm_params:
|
||||
search_provider: perplexity
|
||||
api_key: os.environ/PERPLEXITY_API_KEY
|
||||
|
||||
- search_tool_name: tavily-search
|
||||
litellm_params:
|
||||
search_provider: tavily
|
||||
api_key: os.environ/TAVILY_API_KEY
|
||||
```
|
||||
|
||||
**How search tool selection works:**
|
||||
- If `search_tool_name` is specified → Uses that specific search tool
|
||||
- If `search_tool_name` is not specified → Uses first search tool in `search_tools` list
|
||||
- In example above: Without `search_tool_name`, would use `perplexity-search` (first in list)
|
||||
|
||||
## Related
|
||||
|
||||
- [Claude Code Quickstart](./claude_responses_api.md)
|
||||
- [Claude Code Cost Tracking](./claude_code_customer_tracking.md)
|
||||
- [Using Non-Anthropic Models](./claude_non_anthropic_models.md)
|
||||
|
|
@ -1,15 +1,11 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Claude MCP Quickstart
|
||||
# Use Claude Code with MCPs
|
||||
|
||||
This tutorial shows how to connect MCP servers to Claude Code via LiteLLM Proxy.
|
||||
|
||||
:::info
|
||||
|
||||
This tutorial is based on [Anthropic's official LiteLLM configuration documentation](https://docs.anthropic.com/en/docs/claude-code/llm-gateway#litellm-configuration). This integration allows you to use any LiteLLM supported model through Claude Code with centralized authentication, usage tracking, and cost controls.
|
||||
|
||||
:::
|
||||
Note: LiteLLM supports OAuth for MCP servers as well. [Learn more](https://docs.litellm.ai/docs/mcp#mcp-oauth)
|
||||
|
||||
## Connecting MCP Servers
|
||||
|
||||
|
|
@ -95,4 +91,3 @@ d. Start Oauth flow via Claude Code
|
|||
e. Once completed, you should see this success message:
|
||||
|
||||
<img src={require('../../img/oauth_2_success.png').default} alt="OAuth 2.0 Success" style={{ width: '500px', height: 'auto' }} />
|
||||
|
||||
|
|
|
|||
316
docs/my-website/docs/tutorials/claude_non_anthropic_models.md
Normal file
316
docs/my-website/docs/tutorials/claude_non_anthropic_models.md
Normal file
|
|
@ -0,0 +1,316 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Use Claude Code with Non-Anthropic Models
|
||||
|
||||
This tutorial shows how to use Claude Code with non-Anthropic models like OpenAI, Gemini, and other LLM providers through LiteLLM proxy.
|
||||
|
||||
:::info
|
||||
|
||||
LiteLLM automatically translates between different provider formats, allowing you to use any supported LLM provider with Claude Code while maintaining the Anthropic Messages API format.
|
||||
|
||||
:::
|
||||
|
||||
## Prerequisites
|
||||
|
||||
- [Claude Code](https://docs.anthropic.com/en/docs/claude-code/overview) installed
|
||||
- API keys for your chosen providers (OpenAI, Vertex AI, etc.)
|
||||
|
||||
## Installation
|
||||
|
||||
First, install LiteLLM with proxy support:
|
||||
|
||||
```bash
|
||||
pip install 'litellm[proxy]'
|
||||
```
|
||||
|
||||
## Configuration
|
||||
|
||||
### 1. Setup config.yaml
|
||||
|
||||
Create a configuration file with your preferred non-Anthropic models:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="openai" label="OpenAI">
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
# OpenAI GPT-4o
|
||||
- model_name: gpt-4o
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
# OpenAI GPT-4o-mini
|
||||
- model_name: gpt-4o-mini
|
||||
litellm_params:
|
||||
model: openai/gpt-4o-mini
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
```
|
||||
|
||||
Set your environment variables:
|
||||
|
||||
```bash
|
||||
export OPENAI_API_KEY="your-openai-api-key"
|
||||
export LITELLM_MASTER_KEY="sk-1234567890" # Generate a secure key
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="gemini" label="Google AI Studio">
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
# Google Gemini
|
||||
- model_name: gemini-3.0-flash-exp
|
||||
litellm_params:
|
||||
model: gemini/gemini-3.0-flash-exp
|
||||
api_key: os.environ/GEMINI_API_KEY
|
||||
```
|
||||
|
||||
Set your environment variables:
|
||||
|
||||
```bash
|
||||
export GEMINI_API_KEY="your-gemini-api-key"
|
||||
export LITELLM_MASTER_KEY="sk-1234567890" # Generate a secure key
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="vertex_ai" label="Vertex AI">
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
# Google Gemini
|
||||
- model_name: vertex-gemini-3-flash-preview
|
||||
litellm_params:
|
||||
model: vertex_ai/gemini-3-flash-preview
|
||||
vertex_credentials: os.environ/VERTEX_FILE_PATH_ENV_VAR # os.environ["VERTEX_FILE_PATH_ENV_VAR"] = "/path/to/service_account.json"
|
||||
vertex_project: "my-test-project"
|
||||
vertex_location: "us-east-1"
|
||||
|
||||
# Anthropic Claude
|
||||
- model_name: anthropic-vertex
|
||||
litellm_params:
|
||||
model: vertex_ai/claude-3-sonnet@20240229
|
||||
vertex_ai_project: "my-test-project"
|
||||
vertex_ai_location: "us-east-1"
|
||||
vertex_credentials: os.environ/VERTEX_FILE_PATH_ENV_VAR # os.environ["VERTEX_FILE_PATH_ENV_VAR"] = "/path/to/service_account.json"
|
||||
```
|
||||
|
||||
Set your environment variables:
|
||||
|
||||
```bash
|
||||
export VERTEX_FILE_PATH_ENV_VAR="/path/to/service_account.json"
|
||||
export LITELLM_MASTER_KEY="sk-1234567890"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="multi" label="Azure OpenAI">
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
# Azure OpenAI
|
||||
- model_name: azure-gpt-4
|
||||
litellm_params:
|
||||
model: azure/gpt-4
|
||||
api_key: os.environ/AZURE_API_KEY
|
||||
api_base: os.environ/AZURE_API_BASE
|
||||
api_version: "2024-02-01"
|
||||
```
|
||||
|
||||
Set your environment variables:
|
||||
|
||||
```bash
|
||||
export AZURE_API_KEY="your-azure-api-key"
|
||||
export AZURE_API_BASE="https://your-resource.openai.azure.com"
|
||||
export LITELLM_MASTER_KEY="sk-1234567890"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### 2. Start LiteLLM Proxy
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
### 3. Verify Setup
|
||||
|
||||
Test that your proxy is working correctly:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="openai-test" label="OpenAI">
|
||||
|
||||
```bash
|
||||
curl -X POST http://0.0.0.0:4000/v1/messages \
|
||||
-H "Authorization: Bearer $LITELLM_MASTER_KEY" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "gpt-4o",
|
||||
"max_tokens": 1000,
|
||||
"messages": [{"role": "user", "content": "What is the capital of France?"}]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="gemini-test" label="Google AI Studio">
|
||||
|
||||
```bash
|
||||
curl -X POST http://0.0.0.0:4000/v1/messages \
|
||||
-H "Authorization: Bearer $LITELLM_MASTER_KEY" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "gemini-3.0-flash-exp",
|
||||
"max_tokens": 1000,
|
||||
"messages": [{"role": "user", "content": "What is the capital of France?"}]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="vertex-test" label="Vertex AI">
|
||||
|
||||
```bash
|
||||
curl -X POST http://0.0.0.0:4000/v1/messages \
|
||||
-H "Authorization: Bearer $LITELLM_MASTER_KEY" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "gemini-3.0-flash-exp",
|
||||
"max_tokens": 1000,
|
||||
"messages": [{"role": "user", "content": "What is the capital of France?"}]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="azure-test" label="Azure OpenAI">
|
||||
|
||||
```bash
|
||||
curl -X POST http://0.0.0.0:4000/v1/messages \
|
||||
-H "Authorization: Bearer $LITELLM_MASTER_KEY" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "azure-gpt-4",
|
||||
"max_tokens": 1000,
|
||||
"messages": [{"role": "user", "content": "What is the capital of France?"}]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### 4. Configure Claude Code
|
||||
|
||||
Configure Claude Code to use your LiteLLM proxy:
|
||||
|
||||
```bash
|
||||
export ANTHROPIC_BASE_URL="http://0.0.0.0:4000"
|
||||
export ANTHROPIC_AUTH_TOKEN="$LITELLM_MASTER_KEY"
|
||||
```
|
||||
|
||||
:::tip
|
||||
The `LITELLM_MASTER_KEY` gives Claude Code access to all proxy models. You can also create virtual keys in the LiteLLM UI to limit access to specific models.
|
||||
:::
|
||||
|
||||
### 5. Use Claude Code with Non-Anthropic Models
|
||||
|
||||
Start Claude Code and specify which model to use:
|
||||
|
||||
```bash
|
||||
# Use OpenAI GPT-4o
|
||||
claude --model gpt-4o
|
||||
|
||||
# Use OpenAI GPT-4o-mini for faster responses
|
||||
claude --model gpt-4o-mini
|
||||
|
||||
# Use Google Gemini
|
||||
claude --model gemini-3.0-flash-exp
|
||||
|
||||
# Use Vertex AI Gemini
|
||||
claude --model vertex-gemini-3-flash-preview
|
||||
|
||||
# Use Vertex AI Anthropic Claude
|
||||
claude --model anthropic-vertex
|
||||
|
||||
# Use Azure OpenAI
|
||||
claude --model azure-gpt-4
|
||||
```
|
||||
|
||||
## How It Works
|
||||
|
||||
LiteLLM acts as a unified interface that:
|
||||
|
||||
1. **Receives requests** from Claude Code in Anthropic Messages API format
|
||||
2. **Translates** the request to the target provider's format (OpenAI, Gemini, etc.)
|
||||
3. **Forwards** the request to the actual provider
|
||||
4. **Translates** the response back to Anthropic Messages API format
|
||||
5. **Returns** the response to Claude Code
|
||||
|
||||
This allows you to use Claude Code's interface with any LLM provider supported by LiteLLM.
|
||||
|
||||
## Advanced Features
|
||||
|
||||
### Load Balancing and Fallbacks
|
||||
|
||||
Configure multiple deployments with automatic fallback:
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-4o # virtual model name
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
- model_name: gpt-4o # same virtual name
|
||||
litellm_params:
|
||||
model: azure/gpt-4o
|
||||
api_key: os.environ/AZURE_API_KEY
|
||||
api_base: os.environ/AZURE_API_BASE
|
||||
|
||||
router_settings:
|
||||
routing_strategy: simple-shuffle # Load balance between deployments
|
||||
num_retries: 2
|
||||
timeout: 30
|
||||
```
|
||||
|
||||
### Usage Tracking and Budgets
|
||||
|
||||
Track usage and set budgets through the LiteLLM UI:
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
master_key: os.environ/LITELLM_MASTER_KEY
|
||||
database_url: "postgresql://..." # Enable database for tracking
|
||||
|
||||
general_settings:
|
||||
store_model_in_db: true
|
||||
```
|
||||
|
||||
Start the proxy with the UI:
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml --detailed_debug
|
||||
```
|
||||
|
||||
Access the UI at `http://0.0.0.0:4000/ui` to:
|
||||
- View usage analytics
|
||||
- Set budget limits per user/key
|
||||
- Monitor costs across different providers
|
||||
- Create virtual keys with specific permissions
|
||||
|
||||
|
||||
## Supported Providers
|
||||
|
||||
LiteLLM supports 100+ providers. Here are some popular ones for use with Claude Code:
|
||||
|
||||
- **OpenAI**: GPT-4o, GPT-4o-mini, o1, o3-mini
|
||||
- **Google**: Gemini 2.0 Flash, Gemini 1.5 Pro/Flash
|
||||
- **Azure OpenAI**: All OpenAI models via Azure
|
||||
- **AWS Bedrock**: Llama, Mistral, and other models
|
||||
- **Vertex AI**: Gemini, Claude, and other models on Google Cloud
|
||||
- **Groq**: Fast inference for Llama and Mixtral
|
||||
- **Together AI**: Llama, Mixtral, and other open source models
|
||||
- **Deepseek**: Deepseek-chat, Deepseek-coder
|
||||
|
||||
[View full list of supported providers →](https://docs.litellm.ai/docs/providers)
|
||||
|
|
@ -142,7 +142,7 @@ Common issues and solutions:
|
|||
- Ensure the model name in Claude Code matches exactly with your `config.yaml`
|
||||
- Check LiteLLM logs for detailed error messages
|
||||
|
||||
## Using Multiple Models
|
||||
## Using Bedrock/Vertex AI/Azure Foundry Models
|
||||
|
||||
Expand your configuration to support multiple providers and models:
|
||||
|
||||
|
|
@ -151,25 +151,6 @@ Expand your configuration to support multiple providers and models:
|
|||
|
||||
```yaml
|
||||
model_list:
|
||||
# OpenAI models
|
||||
- model_name: codex-mini
|
||||
litellm_params:
|
||||
model: openai/codex-mini
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
api_base: https://api.openai.com/v1
|
||||
|
||||
- model_name: o3-pro
|
||||
litellm_params:
|
||||
model: openai/o3-pro
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
api_base: https://api.openai.com/v1
|
||||
|
||||
- model_name: gpt-4o
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
api_base: https://api.openai.com/v1
|
||||
|
||||
# Anthropic models
|
||||
- model_name: claude-3-5-sonnet-20241022
|
||||
litellm_params:
|
||||
|
|
@ -189,6 +170,24 @@ model_list:
|
|||
aws_secret_access_key: os.environ/AWS_SECRET_ACCESS_KEY
|
||||
aws_region_name: us-east-1
|
||||
|
||||
# Azure Foundry
|
||||
- model_name: claude-4-azure
|
||||
litellm_params:
|
||||
model: azure_ai/claude-opus-4-1
|
||||
api_key: os.environ/AZURE_AI_API_KEY
|
||||
api_base: os.environ/AZURE_AI_API_BASE # https://my-resource.services.ai.azure.com/anthropic
|
||||
|
||||
# Google Vertex AI
|
||||
- model_name: anthropic-vertex
|
||||
litellm_params:
|
||||
model: vertex_ai/claude-haiku-4-5@20251001
|
||||
vertex_ai_project: "my-test-project"
|
||||
vertex_ai_location: "us-east-1"
|
||||
vertex_credentials: os.environ/VERTEX_FILE_PATH_ENV_VAR # os.environ["VERTEX_FILE_PATH_ENV_VAR"] = "/path/to/service_account.json"
|
||||
|
||||
|
||||
|
||||
|
||||
litellm_settings:
|
||||
master_key: os.environ/LITELLM_MASTER_KEY
|
||||
```
|
||||
|
|
@ -204,6 +203,12 @@ claude --model claude-3-5-haiku-20241022
|
|||
|
||||
# Use Bedrock deployment
|
||||
claude --model claude-bedrock
|
||||
|
||||
# Use Azure Foundry deployment
|
||||
claude --model claude-4-azure
|
||||
|
||||
# Use Vertex AI deployment
|
||||
claude --model anthropic-vertex
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
|
|
|||
BIN
docs/my-website/img/ui_deleted_keys_table.png
Normal file
BIN
docs/my-website/img/ui_deleted_keys_table.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 360 KiB |

Binary file not shown.
|
Before Width: | Height: | Size: 503 KiB After Width: | Height: | Size: 504 KiB |
|
|
@ -1,5 +1,5 @@
|
|||
---
|
||||
title: "[Preview] v1.80.15.rc.1 - Manus API Support"
|
||||
title: "v1.80.15-stable - Manus API Support"
|
||||
slug: "v1-80-15"
|
||||
date: 2026-01-10T10:00:00
|
||||
authors:
|
||||
|
|
@ -27,7 +27,7 @@ import TabItem from '@theme/TabItem';
|
|||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
docker.litellm.ai/berriai/litellm:v1.80.15.rc.1
|
||||
docker.litellm.ai/berriai/litellm:v1.80.15-stable.1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
|
@ -638,6 +638,6 @@ Users can now see Endpoint Activity Metrics in the UI.
|
|||
|
||||
## Full Changelog
|
||||
|
||||
**[View complete changelog on GitHub](https://github.com/BerriAI/litellm/compare/v1.80.11.rc.1...v1.80.14.rc.1)**
|
||||
**[View complete changelog on GitHub](https://github.com/BerriAI/litellm/compare/v1.80.11.rc.1...v1.80.15-stable.1)**
|
||||
|
||||
|
||||
|
|
|
|||
487
docs/my-website/release_notes/v1.81.0/index.md
Normal file
487
docs/my-website/release_notes/v1.81.0/index.md
Normal file
|
|
@ -0,0 +1,487 @@
|
|||
---
|
||||
title: "v1.81.0 - Claude Code - Web Search with all LiteLLM Providers"
|
||||
slug: "v1-81-0"
|
||||
date: 2026-01-18T10:00:00
|
||||
authors:
|
||||
- name: Krrish Dholakia
|
||||
title: CEO, LiteLLM
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: CTO, LiteLLM
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Image from '@theme/IdealImage';
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
## Deploy this version
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="docker" label="Docker">
|
||||
|
||||
``` showLineNumbers title="docker run litellm"
|
||||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
docker.litellm.ai/berriai/litellm:v1.81.0
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="pip" label="Pip">
|
||||
|
||||
``` showLineNumbers title="pip install litellm"
|
||||
pip install litellm==1.81.0
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
---
|
||||
|
||||
## Key Highlights
|
||||
|
||||
- **Claude Code** - Support for using web search across Bedrock, Vertex AI, and all LiteLLM providers
|
||||
- **Major Change** - [50MB limit on image URL downloads](#major-change---chatcompletions-image-url-download-size-limit) to improve reliability
|
||||
|
||||
---
|
||||
|
||||
## Major Change - /chat/completions Image URL Download Size Limit
|
||||
|
||||
To improve reliability and prevent memory issues, LiteLLM now includes a configurable **50MB limit** on image URL downloads by default. Previously, there was no limit on image downloads, which could occasionally cause memory issues with very large images.
|
||||
|
||||
### How It Works
|
||||
|
||||
Requests with image URLs exceeding 50MB will receive a helpful error message:
|
||||
|
||||
```bash
|
||||
curl -X POST 'https://your-litellm-proxy.com/chat/completions' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-d '{
|
||||
"model": "gpt-4o",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "text",
|
||||
"text": "What is in this image?"
|
||||
},
|
||||
{
|
||||
"type": "image_url",
|
||||
"image_url": {
|
||||
"url": "https://example.com/very-large-image.jpg"
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
**Error Response:**
|
||||
|
||||
```json
|
||||
{
|
||||
"error": {
|
||||
"message": "Error: Image size (75.50MB) exceeds maximum allowed size (50.0MB). url=https://example.com/very-large-image.jpg",
|
||||
"type": "ImageFetchError"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Configuring the Limit
|
||||
|
||||
The default 50MB limit works well for most use cases, but you can easily adjust it if needed:
|
||||
|
||||
**Increase the limit (e.g., to 100MB):**
|
||||
|
||||
```bash
|
||||
export MAX_IMAGE_URL_DOWNLOAD_SIZE_MB=100
|
||||
```
|
||||
|
||||
**Disable image URL downloads (for security):**
|
||||
|
||||
```bash
|
||||
export MAX_IMAGE_URL_DOWNLOAD_SIZE_MB=0
|
||||
```
|
||||
|
||||
**Docker Configuration:**
|
||||
|
||||
```bash
|
||||
docker run \
|
||||
-e MAX_IMAGE_URL_DOWNLOAD_SIZE_MB=100 \
|
||||
-p 4000:4000 \
|
||||
docker.litellm.ai/berriai/litellm:v1.81.0
|
||||
```
|
||||
|
||||
**Proxy Config (config.yaml):**
|
||||
|
||||
```yaml
|
||||
general_settings:
|
||||
master_key: sk-1234
|
||||
|
||||
# Set via environment variable
|
||||
environment_variables:
|
||||
MAX_IMAGE_URL_DOWNLOAD_SIZE_MB: "100"
|
||||
```
|
||||
|
||||
### Why Add This?
|
||||
|
||||
This feature improves reliability by:
|
||||
- Preventing memory issues from very large images
|
||||
- Aligning with OpenAI's 50MB payload limit
|
||||
- Validating image sizes early (when Content-Length header is available)
|
||||
|
||||
---
|
||||
|
||||
## New Models / Updated Models
|
||||
|
||||
#### New Model Support
|
||||
|
||||
| Provider | Model | Features |
|
||||
| -------- | ----- | -------- |
|
||||
| OpenAI | `gpt-5.2-codex` | Code generation |
|
||||
| Azure | `azure/gpt-5.2-codex` | Code generation |
|
||||
| Cerebras | `cerebras/zai-glm-4.7` | Reasoning, function calling |
|
||||
| Replicate | All chat models | Full support for all Replicate chat models |
|
||||
|
||||
#### Features
|
||||
|
||||
- **[Anthropic](../../docs/providers/anthropic)**
|
||||
- Add missing anthropic tool results in response - [PR #18945](https://github.com/BerriAI/litellm/pull/18945)
|
||||
- Preserve web_fetch_tool_result in multi-turn conversations - [PR #18142](https://github.com/BerriAI/litellm/pull/18142)
|
||||
|
||||
- **[Gemini](../../docs/providers/gemini)**
|
||||
- Add presence_penalty support for Google AI Studio - [PR #18154](https://github.com/BerriAI/litellm/pull/18154)
|
||||
- Forward extra_headers in generateContent adapter - [PR #18935](https://github.com/BerriAI/litellm/pull/18935)
|
||||
- Add medium value support for detail param - [PR #19187](https://github.com/BerriAI/litellm/pull/19187)
|
||||
|
||||
- **[Vertex AI](../../docs/providers/vertex)**
|
||||
- Improve passthrough endpoint URL parsing and construction - [PR #17526](https://github.com/BerriAI/litellm/pull/17526)
|
||||
- Add type object to tool schemas missing type field - [PR #19103](https://github.com/BerriAI/litellm/pull/19103)
|
||||
- Keep type field in Gemini schema when properties is empty - [PR #18979](https://github.com/BerriAI/litellm/pull/18979)
|
||||
|
||||
- **[Bedrock](../../docs/providers/bedrock)**
|
||||
- Add OpenAI-compatible service_tier parameter translation - [PR #18091](https://github.com/BerriAI/litellm/pull/18091)
|
||||
- Add user auth in standard logging object for Bedrock passthrough - [PR #19140](https://github.com/BerriAI/litellm/pull/19140)
|
||||
- Strip throughput tier suffixes from model names - [PR #19147](https://github.com/BerriAI/litellm/pull/19147)
|
||||
|
||||
- **[OCI](../../docs/providers/oci)**
|
||||
- Handle OpenAI-style image_url object in multimodal messages - [PR #18272](https://github.com/BerriAI/litellm/pull/18272)
|
||||
|
||||
- **[Ollama](../../docs/providers/ollama)**
|
||||
- Set finish_reason to tool_calls and remove broken capability check - [PR #18924](https://github.com/BerriAI/litellm/pull/18924)
|
||||
|
||||
- **[Watsonx](../../docs/providers/watsonx/index)**
|
||||
- Allow passing scope ID for Watsonx inferencing - [PR #18959](https://github.com/BerriAI/litellm/pull/18959)
|
||||
|
||||
- **[Replicate](../../docs/providers/replicate)**
|
||||
- Add all chat Replicate models support - [PR #18954](https://github.com/BerriAI/litellm/pull/18954)
|
||||
|
||||
- **[OpenRouter](../../docs/providers/openrouter)**
|
||||
- Add OpenRouter support for image/generation endpoints - [PR #19059](https://github.com/BerriAI/litellm/pull/19059)
|
||||
|
||||
- **[Volcengine](../../docs/providers/volcano)**
|
||||
- Add max_tokens settings for Volcengine models (deepseek-v3-2, glm-4-7, kimi-k2-thinking) - [PR #19076](https://github.com/BerriAI/litellm/pull/19076)
|
||||
|
||||
- **Azure Model Router**
|
||||
- New Model - Azure Model Router on LiteLLM AI Gateway - [PR #19054](https://github.com/BerriAI/litellm/pull/19054)
|
||||
|
||||
- **GPT-5 Models**
|
||||
- Correct context window sizes for GPT-5 model variants - [PR #18928](https://github.com/BerriAI/litellm/pull/18928)
|
||||
- Correct max_input_tokens for GPT-5 models - [PR #19056](https://github.com/BerriAI/litellm/pull/19056)
|
||||
|
||||
- **Text Completion**
|
||||
- Support token IDs (list of integers) as prompt - [PR #18011](https://github.com/BerriAI/litellm/pull/18011)
|
||||
|
||||
### Bug Fixes
|
||||
|
||||
- **[Anthropic](../../docs/providers/anthropic)**
|
||||
- Prevent dropping thinking when any message has thinking_blocks - [PR #18929](https://github.com/BerriAI/litellm/pull/18929)
|
||||
- Fix anthropic token counter with thinking - [PR #19067](https://github.com/BerriAI/litellm/pull/19067)
|
||||
- Add better error handling for Anthropic - [PR #18955](https://github.com/BerriAI/litellm/pull/18955)
|
||||
- Fix Anthropic during call error - [PR #19060](https://github.com/BerriAI/litellm/pull/19060)
|
||||
|
||||
- **[Gemini](../../docs/providers/gemini)**
|
||||
- Fix missing `completion_tokens_details` in Gemini 3 Flash when reasoning_effort is not used - [PR #18898](https://github.com/BerriAI/litellm/pull/18898)
|
||||
- Fix Gemini Image Generation imageConfig parameters - [PR #18948](https://github.com/BerriAI/litellm/pull/18948)
|
||||
|
||||
- **[Vertex AI](../../docs/providers/vertex)**
|
||||
- Fix Vertex AI 400 Error with CachedContent model mismatch - [PR #19193](https://github.com/BerriAI/litellm/pull/19193)
|
||||
- Fix Vertex AI doesn't support structured output - [PR #19201](https://github.com/BerriAI/litellm/pull/19201)
|
||||
|
||||
- **[Bedrock](../../docs/providers/bedrock)**
|
||||
- Fix Claude Code (`/messages`) Bedrock Invoke usage and request signing - [PR #19111](https://github.com/BerriAI/litellm/pull/19111)
|
||||
- Fix model ID encoding for Bedrock passthrough - [PR #18944](https://github.com/BerriAI/litellm/pull/18944)
|
||||
- Respect max_completion_tokens in thinking feature - [PR #18946](https://github.com/BerriAI/litellm/pull/18946)
|
||||
- Fix header forwarding in Bedrock passthrough - [PR #19007](https://github.com/BerriAI/litellm/pull/19007)
|
||||
- Fix Bedrock stability model usage issues - [PR #19199](https://github.com/BerriAI/litellm/pull/19199)
|
||||
|
||||
---
|
||||
|
||||
## LLM API Endpoints
|
||||
|
||||
#### Features
|
||||
|
||||
- **[/messages (Claude Code)](../../docs/providers/anthropic)**
|
||||
- Add support for Tool Search on `/messages` API across Azure, Bedrock, and Anthropic API - [PR #19165](https://github.com/BerriAI/litellm/pull/19165)
|
||||
- Track end-users with Claude Code (`/messages`) for better analytics and monitoring - [PR #19171](https://github.com/BerriAI/litellm/pull/19171)
|
||||
- Add web search support using LiteLLM `/search` endpoint with Claude Code (`/messages`) - [PR #19263](https://github.com/BerriAI/litellm/pull/19263), [PR #19294](https://github.com/BerriAI/litellm/pull/19294)
|
||||
|
||||
- **[/messages (Claude Code) - Bedrock](../../docs/providers/bedrock)**
|
||||
- Add support for Prompt Caching with Bedrock Converse on `/messages` - [PR #19123](https://github.com/BerriAI/litellm/pull/19123)
|
||||
- Ensure budget tokens are passed to Bedrock Converse API correctly on `/messages` - [PR #19107](https://github.com/BerriAI/litellm/pull/19107)
|
||||
|
||||
- **[Responses API](../../docs/response_api)**
|
||||
- Add support for caching for responses API - [PR #19068](https://github.com/BerriAI/litellm/pull/19068)
|
||||
- Add retry policy support to responses API - [PR #19074](https://github.com/BerriAI/litellm/pull/19074)
|
||||
|
||||
- **Realtime API**
|
||||
- Use non-streaming method for endpoint v1/a2a/message/send - [PR #19025](https://github.com/BerriAI/litellm/pull/19025)
|
||||
|
||||
- **Batch API**
|
||||
- Fix batch deletion and retrieve - [PR #18340](https://github.com/BerriAI/litellm/pull/18340)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- **General**
|
||||
- Fix responses content can't be none - [PR #19064](https://github.com/BerriAI/litellm/pull/19064)
|
||||
- Fix model name from query param in realtime request - [PR #19135](https://github.com/BerriAI/litellm/pull/19135)
|
||||
- Fix video status/content credential injection for wildcard models - [PR #18854](https://github.com/BerriAI/litellm/pull/18854)
|
||||
|
||||
---
|
||||
|
||||
## Management Endpoints / UI
|
||||
|
||||
#### Features
|
||||
|
||||
**Virtual Keys**
|
||||
- View deleted keys for audit purposes - [PR #18228](https://github.com/BerriAI/litellm/pull/18228), [PR #19268](https://github.com/BerriAI/litellm/pull/19268)
|
||||
- Add status query parameter for keys list - [PR #19260](https://github.com/BerriAI/litellm/pull/19260)
|
||||
- Refetch keys after key creation - [PR #18994](https://github.com/BerriAI/litellm/pull/18994)
|
||||
- Refresh keys list on delete - [PR #19262](https://github.com/BerriAI/litellm/pull/19262)
|
||||
- Simplify key generate permission error - [PR #18997](https://github.com/BerriAI/litellm/pull/18997)
|
||||
- Add search to key edit team dropdown - [PR #19119](https://github.com/BerriAI/litellm/pull/19119)
|
||||
|
||||
**Teams & Organizations**
|
||||
- View deleted teams for audit purposes - [PR #18228](https://github.com/BerriAI/litellm/pull/18228), [PR #19268](https://github.com/BerriAI/litellm/pull/19268)
|
||||
- Add filters to organization table - [PR #18916](https://github.com/BerriAI/litellm/pull/18916)
|
||||
- Add query parameters to `/organization/list` - [PR #18910](https://github.com/BerriAI/litellm/pull/18910)
|
||||
- Add status query parameter for teams list - [PR #19260](https://github.com/BerriAI/litellm/pull/19260)
|
||||
- Show internal users their spend only - [PR #19227](https://github.com/BerriAI/litellm/pull/19227)
|
||||
- Allow preventing team admins from deleting members from teams - [PR #19128](https://github.com/BerriAI/litellm/pull/19128)
|
||||
- Refactor team member icon buttons - [PR #19192](https://github.com/BerriAI/litellm/pull/19192)
|
||||
|
||||
**Models + Endpoints**
|
||||
- Display health information in public model hub - [PR #19256](https://github.com/BerriAI/litellm/pull/19256), [PR #19258](https://github.com/BerriAI/litellm/pull/19258)
|
||||
- Quality of life improvements for Anthropic models - [PR #19058](https://github.com/BerriAI/litellm/pull/19058)
|
||||
- Create reusable model select component - [PR #19164](https://github.com/BerriAI/litellm/pull/19164)
|
||||
- Edit settings model dropdown - [PR #19186](https://github.com/BerriAI/litellm/pull/19186)
|
||||
- Fix model hub client side exception - [PR #19045](https://github.com/BerriAI/litellm/pull/19045)
|
||||
|
||||
**Usage & Analytics**
|
||||
- Allow top virtual keys and models to show more entries - [PR #19050](https://github.com/BerriAI/litellm/pull/19050)
|
||||
- Fix Y axis on model activity chart - [PR #19055](https://github.com/BerriAI/litellm/pull/19055)
|
||||
- Add Team ID and Team Name in export report - [PR #19047](https://github.com/BerriAI/litellm/pull/19047)
|
||||
- Add user metrics for Prometheus - [PR #18785](https://github.com/BerriAI/litellm/pull/18785)
|
||||
|
||||
**SSO & Auth**
|
||||
- Allow setting custom MSFT Base URLs - [PR #18977](https://github.com/BerriAI/litellm/pull/18977)
|
||||
- Allow overriding env var attribute names - [PR #18998](https://github.com/BerriAI/litellm/pull/18998)
|
||||
- Fix SCIM GET /Users error and enforce SCIM 2.0 compliance - [PR #17420](https://github.com/BerriAI/litellm/pull/17420)
|
||||
- Feature flag for SCIM compliance fix - [PR #18878](https://github.com/BerriAI/litellm/pull/18878)
|
||||
|
||||
**General UI**
|
||||
- Add allowClear to dropdown components for better UX - [PR #18778](https://github.com/BerriAI/litellm/pull/18778)
|
||||
- Add community engagement buttons - [PR #19114](https://github.com/BerriAI/litellm/pull/19114)
|
||||
- UI Feedback Form - why LiteLLM - [PR #18999](https://github.com/BerriAI/litellm/pull/18999)
|
||||
- Refactor user and team table filters to reusable component - [PR #19010](https://github.com/BerriAI/litellm/pull/19010)
|
||||
- Adjusting new badges - [PR #19278](https://github.com/BerriAI/litellm/pull/19278)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- Container API routes return 401 for non-admin users - routes missing from openai_routes - [PR #19115](https://github.com/BerriAI/litellm/pull/19115)
|
||||
- Allow routing to regional endpoints for Containers API - [PR #19118](https://github.com/BerriAI/litellm/pull/19118)
|
||||
- Fix Azure Storage circular reference error - [PR #19120](https://github.com/BerriAI/litellm/pull/19120)
|
||||
- Fix prompt deletion fails with Prisma FieldNotFoundError - [PR #18966](https://github.com/BerriAI/litellm/pull/18966)
|
||||
|
||||
---
|
||||
|
||||
## AI Integrations
|
||||
|
||||
### Logging
|
||||
|
||||
- **[OpenTelemetry](../../docs/proxy/logging#opentelemetry)**
|
||||
- Update semantic conventions to 1.38 (gen_ai attributes) - [PR #18793](https://github.com/BerriAI/litellm/pull/18793)
|
||||
|
||||
- **[LangSmith](../../docs/proxy/logging#langsmith)**
|
||||
- Hoist thread grouping metadata (session_id, thread) - [PR #18982](https://github.com/BerriAI/litellm/pull/18982)
|
||||
|
||||
- **[Langfuse](../../docs/proxy/logging#langfuse)**
|
||||
- Include Langfuse logger in JSON logging when Langfuse callback is used - [PR #19162](https://github.com/BerriAI/litellm/pull/19162)
|
||||
|
||||
- **[Logfire](../../docs/observability/logfire)**
|
||||
- Add ability to customize Logfire base URL through env var - [PR #19148](https://github.com/BerriAI/litellm/pull/19148)
|
||||
|
||||
- **General Logging**
|
||||
- Enable JSON logging via configuration and add regression test - [PR #19037](https://github.com/BerriAI/litellm/pull/19037)
|
||||
- Fix header forwarding for embeddings endpoint - [PR #18960](https://github.com/BerriAI/litellm/pull/18960)
|
||||
- Preserve llm_provider-* headers in error responses - [PR #19020](https://github.com/BerriAI/litellm/pull/19020)
|
||||
- Fix turn_off_message_logging not redacting request messages in proxy_server_request field - [PR #18897](https://github.com/BerriAI/litellm/pull/18897)
|
||||
|
||||
### Guardrails
|
||||
|
||||
- **[Grayswan](../../docs/proxy/guardrails/grayswan)**
|
||||
- Implement fail-open option (default: True) - [PR #18266](https://github.com/BerriAI/litellm/pull/18266)
|
||||
|
||||
- **[Pangea](../../docs/proxy/guardrails/pangea)**
|
||||
- Respect `default_on` during initialization - [PR #18912](https://github.com/BerriAI/litellm/pull/18912)
|
||||
|
||||
- **[Panw Prisma AIRS](../../docs/proxy/guardrails/panw_prisma_airs)**
|
||||
- Add custom violation message support - [PR #19272](https://github.com/BerriAI/litellm/pull/19272)
|
||||
|
||||
- **General Guardrails**
|
||||
- Fix SerializationIterator error and pass tools to guardrail - [PR #18932](https://github.com/BerriAI/litellm/pull/18932)
|
||||
- Properly handle custom guardrails parameters - [PR #18978](https://github.com/BerriAI/litellm/pull/18978)
|
||||
- Use clean error messages for blocked requests - [PR #19023](https://github.com/BerriAI/litellm/pull/19023)
|
||||
- Guardrail moderation support with responses API - [PR #18957](https://github.com/BerriAI/litellm/pull/18957)
|
||||
- Fix model-level guardrails not taking effect - [PR #18895](https://github.com/BerriAI/litellm/pull/18895)
|
||||
|
||||
---
|
||||
|
||||
## Spend Tracking, Budgets and Rate Limiting
|
||||
|
||||
- **Cost Calculation Fixes**
|
||||
- Include IMAGE token count in cost calculation for Gemini models - [PR #18876](https://github.com/BerriAI/litellm/pull/18876)
|
||||
- Fix negative text_tokens when using cache with images - [PR #18768](https://github.com/BerriAI/litellm/pull/18768)
|
||||
- Fix image tokens spend logging for `/images/generations` - [PR #19009](https://github.com/BerriAI/litellm/pull/19009)
|
||||
- Fix incorrect `prompt_tokens_details` in Gemini Image Generation - [PR #19070](https://github.com/BerriAI/litellm/pull/19070)
|
||||
- Fix case-insensitive model cost map lookup - [PR #18208](https://github.com/BerriAI/litellm/pull/18208)
|
||||
|
||||
- **Pricing Updates**
|
||||
- Correct pricing for `openrouter/openai/gpt-oss-20b` - [PR #18899](https://github.com/BerriAI/litellm/pull/18899)
|
||||
- Add pricing for `azure_ai/claude-opus-4-5` - [PR #19003](https://github.com/BerriAI/litellm/pull/19003)
|
||||
- Update Novita models prices - [PR #19005](https://github.com/BerriAI/litellm/pull/19005)
|
||||
- Fix Azure Grok prices - [PR #19102](https://github.com/BerriAI/litellm/pull/19102)
|
||||
- Fix GCP GLM-4.7 pricing - [PR #19172](https://github.com/BerriAI/litellm/pull/19172)
|
||||
- Sync DeepSeek chat/reasoner to V3.2 pricing - [PR #18884](https://github.com/BerriAI/litellm/pull/18884)
|
||||
- Correct cache_read pricing for gemini-2.5-pro models - [PR #18157](https://github.com/BerriAI/litellm/pull/18157)
|
||||
|
||||
- **Budget & Rate Limiting**
|
||||
- Correct budget limit validation operator (>=) for team members - [PR #19207](https://github.com/BerriAI/litellm/pull/19207)
|
||||
- Fix TPM 25% limiting by ensuring priority queue logic - [PR #19092](https://github.com/BerriAI/litellm/pull/19092)
|
||||
- Cleanup spend logs cron verification, fix, and docs - [PR #19085](https://github.com/BerriAI/litellm/pull/19085)
|
||||
|
||||
---
|
||||
|
||||
## MCP Gateway
|
||||
|
||||
- Prevent duplicate MCP reload scheduler registration - [PR #18934](https://github.com/BerriAI/litellm/pull/18934)
|
||||
- Forward MCP extra headers case-insensitively - [PR #18940](https://github.com/BerriAI/litellm/pull/18940)
|
||||
- Fix MCP REST auth checks - [PR #19051](https://github.com/BerriAI/litellm/pull/19051)
|
||||
- Fix generating two telemetry events in responses - [PR #18938](https://github.com/BerriAI/litellm/pull/18938)
|
||||
- Fix MCP chat completions - [PR #19129](https://github.com/BerriAI/litellm/pull/19129)
|
||||
|
||||
---
|
||||
|
||||
## Performance / Loadbalancing / Reliability improvements
|
||||
|
||||
- **Performance Improvements**
|
||||
- Remove bottleneck causing high CPU usage & overhead under heavy load - [PR #19049](https://github.com/BerriAI/litellm/pull/19049)
|
||||
- Add CI enforcement for O(1) operations in `_get_model_cost_key` to prevent performance regressions - [PR #19052](https://github.com/BerriAI/litellm/pull/19052)
|
||||
- Fix Azure embeddings JSON parsing to prevent connection leaks and ensure proper router cooldown - [PR #19167](https://github.com/BerriAI/litellm/pull/19167)
|
||||
- Do not fallback to token counter if `disable_token_counter` is enabled - [PR #19041](https://github.com/BerriAI/litellm/pull/19041)
|
||||
|
||||
- **Reliability**
|
||||
- Add fallback endpoints support - [PR #19185](https://github.com/BerriAI/litellm/pull/19185)
|
||||
- Fix stream_timeout parameter functionality - [PR #19191](https://github.com/BerriAI/litellm/pull/19191)
|
||||
- Fix model matching priority in configuration - [PR #19012](https://github.com/BerriAI/litellm/pull/19012)
|
||||
- Fix num_retries in litellm_params as per config - [PR #18975](https://github.com/BerriAI/litellm/pull/18975)
|
||||
- Handle exceptions without response parameter - [PR #18919](https://github.com/BerriAI/litellm/pull/18919)
|
||||
|
||||
- **Infrastructure**
|
||||
- Add Custom CA certificates to boto3 clients - [PR #18942](https://github.com/BerriAI/litellm/pull/18942)
|
||||
- Update boto3 to 1.40.15 and aioboto3 to 15.5.0 - [PR #19090](https://github.com/BerriAI/litellm/pull/19090)
|
||||
- Make keepalive_timeout parameter work for Gunicorn - [PR #19087](https://github.com/BerriAI/litellm/pull/19087)
|
||||
|
||||
- **Helm Chart**
|
||||
- Fix mount config.yaml as single file in Helm chart - [PR #19146](https://github.com/BerriAI/litellm/pull/19146)
|
||||
- Sync Helm chart versioning with production standards and Docker versions - [PR #18868](https://github.com/BerriAI/litellm/pull/18868)
|
||||
|
||||
---
|
||||
|
||||
## Database Changes
|
||||
|
||||
### Schema Updates
|
||||
|
||||
| Table | Change Type | Description | PR |
|
||||
| ----- | ----------- | ----------- | -- |
|
||||
| `LiteLLM_ProxyModelTable` | New Columns | Added `created_at` and `updated_at` timestamp fields | [PR #18937](https://github.com/BerriAI/litellm/pull/18937) |
|
||||
|
||||
---
|
||||
|
||||
## Documentation Updates
|
||||
|
||||
- Add LiteLLM architecture md doc - [PR #19057](https://github.com/BerriAI/litellm/pull/19057), [PR #19252](https://github.com/BerriAI/litellm/pull/19252)
|
||||
- Add troubleshooting guide - [PR #19096](https://github.com/BerriAI/litellm/pull/19096), [PR #19097](https://github.com/BerriAI/litellm/pull/19097), [PR #19099](https://github.com/BerriAI/litellm/pull/19099)
|
||||
- Add structured issue reporting guides for CPU and memory issues - [PR #19117](https://github.com/BerriAI/litellm/pull/19117)
|
||||
- Add Redis requirement warning for high-traffic deployments - [PR #18892](https://github.com/BerriAI/litellm/pull/18892)
|
||||
- Update load balancing and routing with enable_pre_call_checks - [PR #18888](https://github.com/BerriAI/litellm/pull/18888)
|
||||
- Updated pass_through with guided param - [PR #18886](https://github.com/BerriAI/litellm/pull/18886)
|
||||
- Update message content types link and add content types table - [PR #18209](https://github.com/BerriAI/litellm/pull/18209)
|
||||
- Add Redis initialization with kwargs - [PR #19183](https://github.com/BerriAI/litellm/pull/19183)
|
||||
- Improve documentation for routing LLM calls via SAP Gen AI Hub - [PR #19166](https://github.com/BerriAI/litellm/pull/19166)
|
||||
- Deleted Keys and Teams docs - [PR #19291](https://github.com/BerriAI/litellm/pull/19291)
|
||||
- Claude Code end user tracking guide - [PR #19176](https://github.com/BerriAI/litellm/pull/19176)
|
||||
- Add MCP troubleshooting guide - [PR #19122](https://github.com/BerriAI/litellm/pull/19122)
|
||||
- Add auth message UI documentation - [PR #19063](https://github.com/BerriAI/litellm/pull/19063)
|
||||
- Add guide for mounting custom callbacks in Helm/K8s - [PR #19136](https://github.com/BerriAI/litellm/pull/19136)
|
||||
|
||||
---
|
||||
|
||||
## Bug Fixes
|
||||
|
||||
- Fix Swagger UI path execute error with server_root_path in OpenAPI schema - [PR #18947](https://github.com/BerriAI/litellm/pull/18947)
|
||||
- Normalize OpenAI SDK BaseModel choices/messages to avoid Pydantic serializer warnings - [PR #18972](https://github.com/BerriAI/litellm/pull/18972)
|
||||
- Add contextual gap checks and word-form digits - [PR #18301](https://github.com/BerriAI/litellm/pull/18301)
|
||||
- Clean up orphaned files from repository root - [PR #19150](https://github.com/BerriAI/litellm/pull/19150)
|
||||
- Include proxy/prisma_migration.py in non-root - [PR #18971](https://github.com/BerriAI/litellm/pull/18971)
|
||||
- Update prisma_migration.py - [PR #19083](https://github.com/BerriAI/litellm/pull/19083)
|
||||
|
||||
---
|
||||
|
||||
## New Contributors
|
||||
|
||||
* @yogeshwaran10 made their first contribution in [PR #18898](https://github.com/BerriAI/litellm/pull/18898)
|
||||
* @theonlypal made their first contribution in [PR #18937](https://github.com/BerriAI/litellm/pull/18937)
|
||||
* @jonmagic made their first contribution in [PR #18935](https://github.com/BerriAI/litellm/pull/18935)
|
||||
* @houdataali made their first contribution in [PR #19025](https://github.com/BerriAI/litellm/pull/19025)
|
||||
* @hummat made their first contribution in [PR #18972](https://github.com/BerriAI/litellm/pull/18972)
|
||||
* @berkeyalciin made their first contribution in [PR #18966](https://github.com/BerriAI/litellm/pull/18966)
|
||||
* @MateuszOssGit made their first contribution in [PR #18959](https://github.com/BerriAI/litellm/pull/18959)
|
||||
* @xfan001 made their first contribution in [PR #18947](https://github.com/BerriAI/litellm/pull/18947)
|
||||
* @nulone made their first contribution in [PR #18884](https://github.com/BerriAI/litellm/pull/18884)
|
||||
* @debnil-mercor made their first contribution in [PR #18919](https://github.com/BerriAI/litellm/pull/18919)
|
||||
* @hakhundov made their first contribution in [PR #17420](https://github.com/BerriAI/litellm/pull/17420)
|
||||
* @rohanwinsor made their first contribution in [PR #19078](https://github.com/BerriAI/litellm/pull/19078)
|
||||
* @pgolm made their first contribution in [PR #19020](https://github.com/BerriAI/litellm/pull/19020)
|
||||
* @vikigenius made their first contribution in [PR #19148](https://github.com/BerriAI/litellm/pull/19148)
|
||||
* @burnerburnerburnerman made their first contribution in [PR #19090](https://github.com/BerriAI/litellm/pull/19090)
|
||||
* @yfge made their first contribution in [PR #19076](https://github.com/BerriAI/litellm/pull/19076)
|
||||
* @danielnyari-seon made their first contribution in [PR #19083](https://github.com/BerriAI/litellm/pull/19083)
|
||||
* @guilherme-segantini made their first contribution in [PR #19166](https://github.com/BerriAI/litellm/pull/19166)
|
||||
* @jgreek made their first contribution in [PR #19147](https://github.com/BerriAI/litellm/pull/19147)
|
||||
* @anand-kamble made their first contribution in [PR #19193](https://github.com/BerriAI/litellm/pull/19193)
|
||||
* @neubig made their first contribution in [PR #19162](https://github.com/BerriAI/litellm/pull/19162)
|
||||
|
||||
---
|
||||
|
||||
## Full Changelog
|
||||
|
||||
**[View complete changelog on GitHub](https://github.com/BerriAI/litellm/compare/v1.80.15.rc.1...v1.81.0.rc.1)**
|
||||
|
|
@ -108,13 +108,23 @@ const sidebars = {
|
|||
{
|
||||
type: "category",
|
||||
label: "AI Tools (OpenWebUI, Claude Code, etc.)",
|
||||
link: {
|
||||
type: "generated-index",
|
||||
title: "AI Tools",
|
||||
description: "Integrate LiteLLM with AI tools like OpenWebUI, Claude Code, and more",
|
||||
slug: "/ai_tools"
|
||||
},
|
||||
items: [
|
||||
"tutorials/openweb_ui",
|
||||
{
|
||||
type: "category",
|
||||
label: "Claude Code",
|
||||
items: [
|
||||
"tutorials/claude_responses_api",
|
||||
"tutorials/claude_code_customer_tracking",
|
||||
"tutorials/claude_code_websearch",
|
||||
"tutorials/claude_mcp",
|
||||
"tutorials/claude_non_anthropic_models",
|
||||
]
|
||||
},
|
||||
"tutorials/cost_tracking_coding",
|
||||
|
|
@ -122,8 +132,7 @@ const sidebars = {
|
|||
"tutorials/github_copilot_integration",
|
||||
"tutorials/litellm_gemini_cli",
|
||||
"tutorials/litellm_qwen_code_cli",
|
||||
"tutorials/openai_codex",
|
||||
"tutorials/openweb_ui"
|
||||
"tutorials/openai_codex"
|
||||
]
|
||||
},
|
||||
|
||||
|
|
@ -266,12 +275,21 @@ const sidebars = {
|
|||
"proxy/ui/bulk_edit_users",
|
||||
"proxy/ui_credentials",
|
||||
"tutorials/scim_litellm",
|
||||
{
|
||||
type: "category",
|
||||
label: "UI Usage Tracking",
|
||||
items: [
|
||||
"proxy/customer_usage",
|
||||
"proxy/endpoint_activity"
|
||||
]
|
||||
},
|
||||
{
|
||||
type: "category",
|
||||
label: "UI Logs",
|
||||
items: [
|
||||
"proxy/ui_logs",
|
||||
"proxy/ui_logs_sessions"
|
||||
"proxy/ui_logs_sessions",
|
||||
"proxy/deleted_keys_teams"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
@ -321,7 +339,6 @@ const sidebars = {
|
|||
"proxy/team_budgets",
|
||||
"proxy/tag_budgets",
|
||||
"proxy/customers",
|
||||
"proxy/customer_usage",
|
||||
"proxy/dynamic_rate_limit",
|
||||
"proxy/rate_limit_tiers",
|
||||
"proxy/temporary_budget_increase",
|
||||
|
|
@ -850,6 +867,7 @@ const sidebars = {
|
|||
"proxy/load_balancing",
|
||||
"proxy/provider_budget_routing",
|
||||
"proxy/reliability",
|
||||
"proxy/fallback_management",
|
||||
"proxy/tag_routing",
|
||||
"proxy/timeout",
|
||||
"wildcard_routing"
|
||||
|
|
@ -869,10 +887,11 @@ const sidebars = {
|
|||
type: "category",
|
||||
label: "Tutorials",
|
||||
items: [
|
||||
"tutorials/openweb_ui",
|
||||
"tutorials/openai_codex",
|
||||
"tutorials/litellm_gemini_cli",
|
||||
"tutorials/litellm_qwen_code_cli",
|
||||
{
|
||||
type: "link",
|
||||
label: "AI Coding Tools (OpenWebUI, Claude Code, Gemini CLI, OpenAI Codex, etc.)",
|
||||
href: "/docs/ai_tools",
|
||||
},
|
||||
"tutorials/anthropic_file_usage",
|
||||
"tutorials/default_team_self_serve",
|
||||
"tutorials/msft_sso",
|
||||
|
|
@ -882,7 +901,6 @@ const sidebars = {
|
|||
"tutorials/presidio_pii_masking",
|
||||
"tutorials/elasticsearch_logging",
|
||||
"tutorials/gemini_realtime_with_audio",
|
||||
"tutorials/claude_responses_api",
|
||||
{
|
||||
type: "category",
|
||||
label: "LiteLLM Python SDK Tutorials",
|
||||
|
|
|
|||
19
document.txt
19
document.txt
|
|
@ -1,19 +0,0 @@
|
|||
LiteLLM provides a unified interface for calling 100+ different LLM providers.
|
||||
|
||||
Key capabilities:
|
||||
- Translate requests to provider-specific formats
|
||||
- Consistent OpenAI-compatible responses
|
||||
- Retry and fallback logic across deployments
|
||||
- Proxy server with authentication and rate limiting
|
||||
- Support for streaming, function calling, and embeddings
|
||||
|
||||
Popular providers supported:
|
||||
- OpenAI (GPT-4, GPT-3.5)
|
||||
- Anthropic (Claude)
|
||||
- AWS Bedrock
|
||||
- Azure OpenAI
|
||||
- Google Vertex AI
|
||||
- Cohere
|
||||
- And 95+ more
|
||||
|
||||
This allows developers to easily switch between providers without code changes.
|
||||

Binary file not shown.
|
Before Width: | Height: | Size: 172 KiB |
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.15-py3-none-any.whl
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.15-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.15.tar.gz
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.15.tar.gz
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.22-py3-none-any.whl
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.22-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.22.tar.gz
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.22.tar.gz
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.23-py3-none-any.whl
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.23-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.23.tar.gz
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.23.tar.gz
vendored
Normal file
Binary file not shown.
|
|
@ -0,0 +1,117 @@
|
|||
-- CreateTable
|
||||
CREATE TABLE "LiteLLM_DeletedTeamTable" (
|
||||
"id" TEXT NOT NULL,
|
||||
"team_id" TEXT NOT NULL,
|
||||
"team_alias" TEXT,
|
||||
"organization_id" TEXT,
|
||||
"object_permission_id" TEXT,
|
||||
"admins" TEXT[],
|
||||
"members" TEXT[],
|
||||
"members_with_roles" JSONB NOT NULL DEFAULT '{}',
|
||||
"metadata" JSONB NOT NULL DEFAULT '{}',
|
||||
"max_budget" DOUBLE PRECISION,
|
||||
"spend" DOUBLE PRECISION NOT NULL DEFAULT 0.0,
|
||||
"models" TEXT[],
|
||||
"max_parallel_requests" INTEGER,
|
||||
"tpm_limit" BIGINT,
|
||||
"rpm_limit" BIGINT,
|
||||
"budget_duration" TEXT,
|
||||
"budget_reset_at" TIMESTAMP(3),
|
||||
"blocked" BOOLEAN NOT NULL DEFAULT false,
|
||||
"model_spend" JSONB NOT NULL DEFAULT '{}',
|
||||
"model_max_budget" JSONB NOT NULL DEFAULT '{}',
|
||||
"team_member_permissions" TEXT[] DEFAULT ARRAY[]::TEXT[],
|
||||
"model_id" INTEGER,
|
||||
"created_at" TIMESTAMP(3),
|
||||
"updated_at" TIMESTAMP(3),
|
||||
"deleted_at" TIMESTAMP(3) NOT NULL DEFAULT CURRENT_TIMESTAMP,
|
||||
"deleted_by" TEXT,
|
||||
"deleted_by_api_key" TEXT,
|
||||
"litellm_changed_by" TEXT,
|
||||
|
||||
CONSTRAINT "LiteLLM_DeletedTeamTable_pkey" PRIMARY KEY ("id")
|
||||
);
|
||||
|
||||
-- CreateTable
|
||||
CREATE TABLE "LiteLLM_DeletedVerificationToken" (
|
||||
"id" TEXT NOT NULL,
|
||||
"token" TEXT NOT NULL,
|
||||
"key_name" TEXT,
|
||||
"key_alias" TEXT,
|
||||
"soft_budget_cooldown" BOOLEAN NOT NULL DEFAULT false,
|
||||
"spend" DOUBLE PRECISION NOT NULL DEFAULT 0.0,
|
||||
"expires" TIMESTAMP(3),
|
||||
"models" TEXT[],
|
||||
"aliases" JSONB NOT NULL DEFAULT '{}',
|
||||
"config" JSONB NOT NULL DEFAULT '{}',
|
||||
"user_id" TEXT,
|
||||
"team_id" TEXT,
|
||||
"permissions" JSONB NOT NULL DEFAULT '{}',
|
||||
"max_parallel_requests" INTEGER,
|
||||
"metadata" JSONB NOT NULL DEFAULT '{}',
|
||||
"blocked" BOOLEAN,
|
||||
"tpm_limit" BIGINT,
|
||||
"rpm_limit" BIGINT,
|
||||
"max_budget" DOUBLE PRECISION,
|
||||
"budget_duration" TEXT,
|
||||
"budget_reset_at" TIMESTAMP(3),
|
||||
"allowed_cache_controls" TEXT[] DEFAULT ARRAY[]::TEXT[],
|
||||
"allowed_routes" TEXT[] DEFAULT ARRAY[]::TEXT[],
|
||||
"model_spend" JSONB NOT NULL DEFAULT '{}',
|
||||
"model_max_budget" JSONB NOT NULL DEFAULT '{}',
|
||||
"budget_id" TEXT,
|
||||
"organization_id" TEXT,
|
||||
"object_permission_id" TEXT,
|
||||
"created_at" TIMESTAMP(3),
|
||||
"created_by" TEXT,
|
||||
"updated_at" TIMESTAMP(3),
|
||||
"updated_by" TEXT,
|
||||
"rotation_count" INTEGER DEFAULT 0,
|
||||
"auto_rotate" BOOLEAN DEFAULT false,
|
||||
"rotation_interval" TEXT,
|
||||
"last_rotation_at" TIMESTAMP(3),
|
||||
"key_rotation_at" TIMESTAMP(3),
|
||||
"deleted_at" TIMESTAMP(3) NOT NULL DEFAULT CURRENT_TIMESTAMP,
|
||||
"deleted_by" TEXT,
|
||||
"deleted_by_api_key" TEXT,
|
||||
"litellm_changed_by" TEXT,
|
||||
|
||||
CONSTRAINT "LiteLLM_DeletedVerificationToken_pkey" PRIMARY KEY ("id")
|
||||
);
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeletedTeamTable_team_id_idx" ON "LiteLLM_DeletedTeamTable"("team_id");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeletedTeamTable_deleted_at_idx" ON "LiteLLM_DeletedTeamTable"("deleted_at");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeletedTeamTable_organization_id_idx" ON "LiteLLM_DeletedTeamTable"("organization_id");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeletedTeamTable_team_alias_idx" ON "LiteLLM_DeletedTeamTable"("team_alias");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeletedTeamTable_created_at_idx" ON "LiteLLM_DeletedTeamTable"("created_at");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeletedVerificationToken_token_idx" ON "LiteLLM_DeletedVerificationToken"("token");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeletedVerificationToken_deleted_at_idx" ON "LiteLLM_DeletedVerificationToken"("deleted_at");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeletedVerificationToken_user_id_idx" ON "LiteLLM_DeletedVerificationToken"("user_id");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeletedVerificationToken_team_id_idx" ON "LiteLLM_DeletedVerificationToken"("team_id");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeletedVerificationToken_organization_id_idx" ON "LiteLLM_DeletedVerificationToken"("organization_id");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeletedVerificationToken_key_alias_idx" ON "LiteLLM_DeletedVerificationToken"("key_alias");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeletedVerificationToken_created_at_idx" ON "LiteLLM_DeletedVerificationToken"("created_at");
|
||||
|
||||
|
|
@ -0,0 +1,6 @@
|
|||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_DeletedTeamTable" ADD COLUMN "router_settings" JSONB DEFAULT '{}';
|
||||
|
||||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_DeletedVerificationToken" ADD COLUMN "router_settings" JSONB DEFAULT '{}';
|
||||
|
||||
|
|
@ -132,6 +132,49 @@ model LiteLLM_TeamTable {
|
|||
object_permission LiteLLM_ObjectPermissionTable? @relation(fields: [object_permission_id], references: [object_permission_id])
|
||||
}
|
||||
|
||||
// Audit table for deleted teams - preserves spend and team information for historical tracking
|
||||
model LiteLLM_DeletedTeamTable {
|
||||
id String @id @default(uuid())
|
||||
team_id String // Original team_id
|
||||
team_alias String?
|
||||
organization_id String?
|
||||
object_permission_id String?
|
||||
admins String[]
|
||||
members String[]
|
||||
members_with_roles Json @default("{}")
|
||||
metadata Json @default("{}")
|
||||
max_budget Float?
|
||||
spend Float @default(0.0)
|
||||
models String[]
|
||||
max_parallel_requests Int?
|
||||
tpm_limit BigInt?
|
||||
rpm_limit BigInt?
|
||||
budget_duration String?
|
||||
budget_reset_at DateTime?
|
||||
blocked Boolean @default(false)
|
||||
model_spend Json @default("{}")
|
||||
model_max_budget Json @default("{}")
|
||||
router_settings Json? @default("{}")
|
||||
team_member_permissions String[] @default([])
|
||||
model_id Int? // id for LiteLLM_ModelTable -> stores team-level model aliases
|
||||
|
||||
// Original timestamps from team creation/updates
|
||||
created_at DateTime? @map("created_at")
|
||||
updated_at DateTime? @map("updated_at")
|
||||
|
||||
// Deletion metadata
|
||||
deleted_at DateTime @default(now()) @map("deleted_at")
|
||||
deleted_by String? @map("deleted_by") // User who deleted the team
|
||||
deleted_by_api_key String? @map("deleted_by_api_key") // API key hash that performed the deletion
|
||||
litellm_changed_by String? @map("litellm_changed_by") // From litellm-changed-by header if provided
|
||||
|
||||
@@index([team_id])
|
||||
@@index([deleted_at])
|
||||
@@index([organization_id])
|
||||
@@index([team_alias])
|
||||
@@index([created_at])
|
||||
}
|
||||
|
||||
// Track spend, rate limit, budget Users
|
||||
model LiteLLM_UserTable {
|
||||
user_id String @id
|
||||
|
|
@ -259,6 +302,62 @@ model LiteLLM_VerificationToken {
|
|||
object_permission LiteLLM_ObjectPermissionTable? @relation(fields: [object_permission_id], references: [object_permission_id])
|
||||
}
|
||||
|
||||
// Audit table for deleted keys - preserves spend and key information for historical tracking
|
||||
model LiteLLM_DeletedVerificationToken {
|
||||
id String @id @default(uuid())
|
||||
token String // Original token (hashed)
|
||||
key_name String?
|
||||
key_alias String?
|
||||
soft_budget_cooldown Boolean @default(false)
|
||||
spend Float @default(0.0)
|
||||
expires DateTime?
|
||||
models String[]
|
||||
aliases Json @default("{}")
|
||||
config Json @default("{}")
|
||||
user_id String?
|
||||
team_id String?
|
||||
permissions Json @default("{}")
|
||||
max_parallel_requests Int?
|
||||
metadata Json @default("{}")
|
||||
blocked Boolean?
|
||||
tpm_limit BigInt?
|
||||
rpm_limit BigInt?
|
||||
max_budget Float?
|
||||
budget_duration String?
|
||||
budget_reset_at DateTime?
|
||||
allowed_cache_controls String[] @default([])
|
||||
allowed_routes String[] @default([])
|
||||
model_spend Json @default("{}")
|
||||
model_max_budget Json @default("{}")
|
||||
router_settings Json? @default("{}")
|
||||
budget_id String?
|
||||
organization_id String?
|
||||
object_permission_id String?
|
||||
created_at DateTime? // Original creation timestamp
|
||||
created_by String? // Original creator
|
||||
updated_at DateTime? // Last update timestamp before deletion
|
||||
updated_by String? // Last user who updated before deletion
|
||||
rotation_count Int? @default(0)
|
||||
auto_rotate Boolean? @default(false)
|
||||
rotation_interval String?
|
||||
last_rotation_at DateTime?
|
||||
key_rotation_at DateTime?
|
||||
|
||||
// Deletion metadata
|
||||
deleted_at DateTime @default(now()) @map("deleted_at")
|
||||
deleted_by String? @map("deleted_by") // User who deleted the key
|
||||
deleted_by_api_key String? @map("deleted_by_api_key") // API key hash that performed the deletion
|
||||
litellm_changed_by String? @map("litellm_changed_by") // From litellm-changed-by header if provided
|
||||
|
||||
@@index([token])
|
||||
@@index([deleted_at])
|
||||
@@index([user_id])
|
||||
@@index([team_id])
|
||||
@@index([organization_id])
|
||||
@@index([key_alias])
|
||||
@@index([created_at])
|
||||
}
|
||||
|
||||
model LiteLLM_EndUserTable {
|
||||
user_id String @id
|
||||
alias String? // admin-facing alias
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "litellm-proxy-extras"
|
||||
version = "0.4.21"
|
||||
version = "0.4.23"
|
||||
description = "Additional files for the LiteLLM Proxy. Reduces the size of the main litellm package."
|
||||
authors = ["BerriAI"]
|
||||
readme = "README.md"
|
||||
|
|
@ -22,7 +22,7 @@ requires = ["poetry-core"]
|
|||
build-backend = "poetry.core.masonry.api"
|
||||
|
||||
[tool.commitizen]
|
||||
version = "0.4.21"
|
||||
version = "0.4.23"
|
||||
version_files = [
|
||||
"pyproject.toml:version",
|
||||
"../requirements.txt:litellm-proxy-extras==",
|
||||
|
|
|
|||
|
|
@ -9,7 +9,7 @@ warnings.filterwarnings("ignore", message=".*conflict with protected namespace.*
|
|||
warnings.filterwarnings(
|
||||
"ignore", message=".*Accessing the.*attribute on the instance is deprecated.*"
|
||||
)
|
||||
### INIT VARIABLES ########################
|
||||
### INIT VARIABLES #########################
|
||||
import threading
|
||||
import os
|
||||
from typing import (
|
||||
|
|
|
|||
|
|
@ -133,6 +133,26 @@ ALL_LOGGERS = [
|
|||
]
|
||||
|
||||
|
||||
def _get_loggers_to_initialize():
|
||||
"""
|
||||
Get all loggers that should be initialized with the JSON handler.
|
||||
|
||||
Includes third-party integration loggers (like langfuse) if they are
|
||||
configured as callbacks.
|
||||
"""
|
||||
import litellm
|
||||
|
||||
loggers = list(ALL_LOGGERS)
|
||||
|
||||
# Add langfuse logger if langfuse is being used as a callback
|
||||
langfuse_callbacks = {"langfuse", "langfuse_otel"}
|
||||
all_callbacks = set(litellm.success_callback + litellm.failure_callback)
|
||||
if langfuse_callbacks & all_callbacks:
|
||||
loggers.append(logging.getLogger("langfuse"))
|
||||
|
||||
return loggers
|
||||
|
||||
|
||||
def _initialize_loggers_with_handler(handler: logging.Handler):
|
||||
"""
|
||||
Initialize all loggers with a handler
|
||||
|
|
@ -140,7 +160,7 @@ def _initialize_loggers_with_handler(handler: logging.Handler):
|
|||
- Adds a handler to each logger
|
||||
- Prevents bubbling to parent/root (critical to prevent duplicate JSON logs)
|
||||
"""
|
||||
for lg in ALL_LOGGERS:
|
||||
for lg in _get_loggers_to_initialize():
|
||||
lg.handlers.clear() # remove any existing handlers
|
||||
lg.addHandler(handler) # add JSON formatter handler
|
||||
lg.propagate = False # prevent bubbling to parent/root
|
||||
|
|
|
|||
|
|
@ -48,6 +48,11 @@ DEFAULT_REPLICATE_POLLING_DELAY_SECONDS = int(
|
|||
DEFAULT_IMAGE_TOKEN_COUNT = int(os.getenv("DEFAULT_IMAGE_TOKEN_COUNT", 250))
|
||||
DEFAULT_IMAGE_WIDTH = int(os.getenv("DEFAULT_IMAGE_WIDTH", 300))
|
||||
DEFAULT_IMAGE_HEIGHT = int(os.getenv("DEFAULT_IMAGE_HEIGHT", 300))
|
||||
# Maximum size for image URL downloads in MB (default 50MB, set to 0 to disable limit)
|
||||
# This prevents memory issues from downloading very large images
|
||||
# Maps to OpenAI's 50 MB payload limit - requests with images exceeding this size will be rejected
|
||||
# Set MAX_IMAGE_URL_DOWNLOAD_SIZE_MB=0 to disable image URL handling entirely
|
||||
MAX_IMAGE_URL_DOWNLOAD_SIZE_MB = float(os.getenv("MAX_IMAGE_URL_DOWNLOAD_SIZE_MB", 50))
|
||||
MAX_SIZE_PER_ITEM_IN_MEMORY_CACHE_IN_KB = int(
|
||||
os.getenv("MAX_SIZE_PER_ITEM_IN_MEMORY_CACHE_IN_KB", 1024)
|
||||
) # 1MB = 1024KB
|
||||
|
|
@ -324,6 +329,11 @@ ANTHROPIC_WEB_SEARCH_TOOL_MAX_USES = {
|
|||
"medium": 5,
|
||||
"high": 10,
|
||||
}
|
||||
|
||||
# LiteLLM standard web search tool name
|
||||
# Used for web search interception across providers
|
||||
LITELLM_WEB_SEARCH_TOOL_NAME = "litellm_web_search"
|
||||
|
||||
DEFAULT_IMAGE_ENDPOINT_MODEL = "dall-e-2"
|
||||
DEFAULT_VIDEO_ENDPOINT_MODEL = "sora-2"
|
||||
|
||||
|
|
@ -1073,6 +1083,13 @@ LITELLM_TRUNCATED_PAYLOAD_FIELD = "litellm_truncated"
|
|||
|
||||
########################### LiteLLM Proxy Specific Constants ###########################
|
||||
########################################################################################
|
||||
|
||||
# Standard headers that are always checked for customer/end-user ID (no configuration required)
|
||||
# These headers work out-of-the-box for tools like Claude Code that support custom headers
|
||||
STANDARD_CUSTOMER_ID_HEADERS = [
|
||||
"x-litellm-customer-id",
|
||||
"x-litellm-end-user-id",
|
||||
]
|
||||
MAX_SPENDLOG_ROWS_TO_QUERY = int(
|
||||
os.getenv("MAX_SPENDLOG_ROWS_TO_QUERY", 1_000_000)
|
||||
) # if spendLogs has more than 1M rows, do not query the DB
|
||||
|
|
|
|||
|
|
@ -952,7 +952,8 @@ def completion_cost( # noqa: PLR0915
|
|||
)
|
||||
|
||||
potential_model_names = [selected_model, _get_response_model(completion_response)]
|
||||
|
||||
if model is not None:
|
||||
potential_model_names.append(model)
|
||||
|
||||
for idx, model in enumerate(potential_model_names):
|
||||
try:
|
||||
|
|
|
|||
|
|
@ -33,10 +33,9 @@ from litellm.types.utils import (
|
|||
|
||||
if TYPE_CHECKING:
|
||||
from fastapi import HTTPException
|
||||
|
||||
from litellm.caching.caching import DualCache
|
||||
from opentelemetry.trace import Span as _Span
|
||||
|
||||
from litellm.caching.caching import DualCache
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj
|
||||
from litellm.proxy._types import UserAPIKeyAuth
|
||||
from litellm.types.mcp import (
|
||||
|
|
@ -144,6 +143,34 @@ class CustomLogger: # https://docs.litellm.ai/docs/observability/custom_callbac
|
|||
async def async_log_pre_api_call(self, model, messages, kwargs):
|
||||
pass
|
||||
|
||||
async def async_pre_request_hook(
|
||||
self, model: str, messages: List, kwargs: Dict
|
||||
) -> Optional[Dict]:
|
||||
"""
|
||||
Hook called before making the API request to allow modifying request parameters.
|
||||
|
||||
This is specifically designed for modifying the request before it's sent to the provider.
|
||||
Unlike async_log_pre_api_call (which is for logging), this hook is meant for transformations.
|
||||
|
||||
Args:
|
||||
model: The model name
|
||||
messages: The messages list
|
||||
kwargs: The request parameters (tools, stream, temperature, etc.)
|
||||
|
||||
Returns:
|
||||
Optional[Dict]: Modified kwargs to use for the request, or None if no modifications
|
||||
|
||||
Example:
|
||||
```python
|
||||
async def async_pre_request_hook(self, model, messages, kwargs):
|
||||
# Convert native tools to standard format
|
||||
if kwargs.get("tools"):
|
||||
kwargs["tools"] = convert_tools(kwargs["tools"])
|
||||
return kwargs
|
||||
```
|
||||
"""
|
||||
pass
|
||||
|
||||
async def async_log_success_event(self, kwargs, response_obj, start_time, end_time):
|
||||
pass
|
||||
|
||||
|
|
@ -484,6 +511,138 @@ class CustomLogger: # https://docs.litellm.ai/docs/observability/custom_callbac
|
|||
"""
|
||||
return None
|
||||
|
||||
#########################################################
|
||||
# AGENTIC LOOP HOOKS (for litellm.messages + future completion support)
|
||||
#########################################################
|
||||
|
||||
async def async_should_run_agentic_loop(
|
||||
self,
|
||||
response: Any,
|
||||
model: str,
|
||||
messages: List[Dict],
|
||||
tools: Optional[List[Dict]],
|
||||
stream: bool,
|
||||
custom_llm_provider: str,
|
||||
kwargs: Dict,
|
||||
) -> Tuple[bool, Dict]:
|
||||
"""
|
||||
Hook to determine if agentic loop should be executed.
|
||||
|
||||
Called after receiving response from model, before returning to user.
|
||||
|
||||
USE CASE: Enables transparent server-side tool execution for models that
|
||||
don't natively support server-side tools. User makes ONE API call and gets
|
||||
back the final answer - the agentic loop happens transparently on the server.
|
||||
|
||||
Example use cases:
|
||||
- WebSearch: Intercept WebSearch tool calls for Bedrock/Claude, execute
|
||||
litellm.search(), return final answer with search results
|
||||
- Code execution: Execute code in sandboxed environment, return results
|
||||
- Database queries: Execute queries server-side, return data to model
|
||||
- API calls: Make external API calls and inject responses back into context
|
||||
|
||||
Flow:
|
||||
1. User calls litellm.messages.acreate(tools=[...])
|
||||
2. Model responds with tool_use
|
||||
3. THIS HOOK checks if tool should run server-side
|
||||
4. If True, async_run_agentic_loop executes the tool
|
||||
5. User receives final answer (never sees intermediate tool_use)
|
||||
|
||||
Args:
|
||||
response: Response from model (AnthropicMessagesResponse or AsyncIterator)
|
||||
model: Model name
|
||||
messages: Original messages sent to model
|
||||
tools: List of tool definitions from request
|
||||
stream: Whether response is streaming
|
||||
custom_llm_provider: Provider name (e.g., "bedrock", "anthropic")
|
||||
kwargs: Additional request parameters
|
||||
|
||||
Returns:
|
||||
(should_run, tools):
|
||||
should_run: True if agentic loop should execute
|
||||
tools: Dict with tool_calls and metadata for execution
|
||||
|
||||
Example:
|
||||
# Detect WebSearch tool call
|
||||
if has_websearch_tool_use(response):
|
||||
return True, {
|
||||
"tool_calls": extract_tool_calls(response),
|
||||
"tool_type": "websearch"
|
||||
}
|
||||
return False, {}
|
||||
"""
|
||||
return False, {}
|
||||
|
||||
async def async_run_agentic_loop(
|
||||
self,
|
||||
tools: Dict,
|
||||
model: str,
|
||||
messages: List[Dict],
|
||||
response: Any,
|
||||
anthropic_messages_provider_config: Any,
|
||||
anthropic_messages_optional_request_params: Dict,
|
||||
logging_obj: "LiteLLMLoggingObj",
|
||||
stream: bool,
|
||||
kwargs: Dict,
|
||||
) -> Any:
|
||||
"""
|
||||
Hook to execute agentic loop based on context from should_run hook.
|
||||
|
||||
Called only if async_messages_should_run_agentic_loop returns True.
|
||||
|
||||
USE CASE: Execute server-side tools and orchestrate the agentic loop to
|
||||
return a complete answer to the user in a single API call.
|
||||
|
||||
What to do here:
|
||||
1. Extract tool calls from tools dict
|
||||
2. Execute the tools (litellm.search, code execution, DB queries, etc.)
|
||||
3. Build assistant message with tool_use blocks
|
||||
4. Build user message with tool_result blocks containing results
|
||||
5. Make follow-up litellm.messages.acreate() call with results
|
||||
6. Return the final response
|
||||
|
||||
Args:
|
||||
tools: Dict from async_should_run_agentic_loop
|
||||
Contains tool_calls and metadata
|
||||
model: Model name
|
||||
messages: Original messages sent to model
|
||||
response: Original response from model (with tool_use)
|
||||
anthropic_messages_provider_config: Provider config for making requests
|
||||
anthropic_messages_optional_request_params: Request parameters (tools, etc.)
|
||||
logging_obj: LiteLLM logging object
|
||||
stream: Whether response is streaming
|
||||
kwargs: Additional request parameters
|
||||
|
||||
Returns:
|
||||
Final response after executing agentic loop
|
||||
(AnthropicMessagesResponse with final answer)
|
||||
|
||||
Example:
|
||||
# Extract tool calls
|
||||
tool_calls = agentic_context["tool_calls"]
|
||||
|
||||
# Execute searches in parallel
|
||||
search_results = await asyncio.gather(
|
||||
*[litellm.asearch(tc["input"]["query"]) for tc in tool_calls]
|
||||
)
|
||||
|
||||
# Build messages with tool results
|
||||
assistant_msg = {"role": "assistant", "content": [...tool_use blocks...]}
|
||||
user_msg = {"role": "user", "content": [...tool_result blocks...]}
|
||||
|
||||
# Make follow-up request
|
||||
from litellm.anthropic_interface import messages
|
||||
final_response = await messages.acreate(
|
||||
model=model,
|
||||
messages=messages + [assistant_msg, user_msg],
|
||||
max_tokens=anthropic_messages_optional_request_params.get("max_tokens"),
|
||||
**anthropic_messages_optional_request_params
|
||||
)
|
||||
|
||||
return final_response
|
||||
"""
|
||||
pass
|
||||
|
||||
# Useful helpers for custom logger classes
|
||||
|
||||
def truncate_standard_logging_payload_content(
|
||||
|
|
|
|||
|
|
@ -21,7 +21,12 @@ from typing import (
|
|||
import litellm
|
||||
from litellm._logging import print_verbose, verbose_logger
|
||||
from litellm.integrations.custom_logger import CustomLogger
|
||||
from litellm.proxy._types import LiteLLM_TeamTable, UserAPIKeyAuth
|
||||
from litellm.proxy._types import (
|
||||
LiteLLM_DeletedVerificationToken,
|
||||
LiteLLM_TeamTable,
|
||||
LiteLLM_UserTable,
|
||||
UserAPIKeyAuth,
|
||||
)
|
||||
from litellm.types.integrations.prometheus import *
|
||||
from litellm.types.integrations.prometheus import _sanitize_prometheus_label_name
|
||||
from litellm.types.utils import StandardLoggingPayload
|
||||
|
|
@ -52,7 +57,7 @@ def _get_cached_end_user_id_for_cost_tracking():
|
|||
|
||||
class PrometheusLogger(CustomLogger):
|
||||
# Class variables or attributes
|
||||
def __init__(
|
||||
def __init__( # noqa: PLR0915
|
||||
self,
|
||||
**kwargs,
|
||||
):
|
||||
|
|
@ -193,6 +198,30 @@ class PrometheusLogger(CustomLogger):
|
|||
),
|
||||
)
|
||||
|
||||
# Remaining Budget for User
|
||||
self.litellm_remaining_user_budget_metric = self._gauge_factory(
|
||||
"litellm_remaining_user_budget_metric",
|
||||
"Remaining budget for user",
|
||||
labelnames=self.get_labels_for_metric(
|
||||
"litellm_remaining_user_budget_metric"
|
||||
),
|
||||
)
|
||||
|
||||
# Max Budget for User
|
||||
self.litellm_user_max_budget_metric = self._gauge_factory(
|
||||
"litellm_user_max_budget_metric",
|
||||
"Maximum budget set for user",
|
||||
labelnames=self.get_labels_for_metric("litellm_user_max_budget_metric"),
|
||||
)
|
||||
|
||||
self.litellm_user_budget_remaining_hours_metric = self._gauge_factory(
|
||||
"litellm_user_budget_remaining_hours_metric",
|
||||
"Remaining hours for user budget to be reset",
|
||||
labelnames=self.get_labels_for_metric(
|
||||
"litellm_user_budget_remaining_hours_metric"
|
||||
),
|
||||
)
|
||||
|
||||
########################################
|
||||
# LiteLLM Virtual API KEY metrics
|
||||
########################################
|
||||
|
|
@ -960,6 +989,7 @@ class PrometheusLogger(CustomLogger):
|
|||
user_api_key_alias=user_api_key_alias,
|
||||
litellm_params=litellm_params,
|
||||
response_cost=response_cost,
|
||||
user_id=user_id,
|
||||
)
|
||||
|
||||
# set proxy virtual key rpm/tpm metrics
|
||||
|
|
@ -1120,6 +1150,7 @@ class PrometheusLogger(CustomLogger):
|
|||
user_api_key_alias: Optional[str],
|
||||
litellm_params: dict,
|
||||
response_cost: float,
|
||||
user_id: Optional[str] = None,
|
||||
):
|
||||
_team_spend = litellm_params.get("metadata", {}).get(
|
||||
"user_api_key_team_spend", None
|
||||
|
|
@ -1134,6 +1165,14 @@ class PrometheusLogger(CustomLogger):
|
|||
_api_key_max_budget = litellm_params.get("metadata", {}).get(
|
||||
"user_api_key_max_budget", None
|
||||
)
|
||||
|
||||
_user_spend = litellm_params.get("metadata", {}).get(
|
||||
"user_api_key_user_spend", None
|
||||
)
|
||||
_user_max_budget = litellm_params.get("metadata", {}).get(
|
||||
"user_api_key_user_max_budget", None
|
||||
)
|
||||
|
||||
await self._set_api_key_budget_metrics_after_api_request(
|
||||
user_api_key=user_api_key,
|
||||
user_api_key_alias=user_api_key_alias,
|
||||
|
|
@ -1150,6 +1189,13 @@ class PrometheusLogger(CustomLogger):
|
|||
response_cost=response_cost,
|
||||
)
|
||||
|
||||
await self._set_user_budget_metrics_after_api_request(
|
||||
user_id=user_id,
|
||||
user_spend=_user_spend,
|
||||
user_max_budget=_user_max_budget,
|
||||
response_cost=response_cost,
|
||||
)
|
||||
|
||||
def _increment_top_level_request_and_spend_metrics(
|
||||
self,
|
||||
end_user_id: Optional[str],
|
||||
|
|
@ -2112,7 +2158,7 @@ class PrometheusLogger(CustomLogger):
|
|||
self,
|
||||
data_fetch_function: Callable[..., Awaitable[Tuple[List[Any], Optional[int]]]],
|
||||
set_metrics_function: Callable[[List[Any]], Awaitable[None]],
|
||||
data_type: Literal["teams", "keys"],
|
||||
data_type: Literal["teams", "keys", "users"],
|
||||
):
|
||||
"""
|
||||
Generic method to initialize budget metrics for teams or API keys.
|
||||
|
|
@ -2204,7 +2250,7 @@ class PrometheusLogger(CustomLogger):
|
|||
|
||||
async def fetch_keys(
|
||||
page_size: int, page: int
|
||||
) -> Tuple[List[Union[str, UserAPIKeyAuth]], Optional[int]]:
|
||||
) -> Tuple[List[Union[str, UserAPIKeyAuth, LiteLLM_DeletedVerificationToken]], Optional[int]]:
|
||||
key_list_response = await _list_key_helper(
|
||||
prisma_client=prisma_client,
|
||||
page=page,
|
||||
|
|
@ -2229,6 +2275,37 @@ class PrometheusLogger(CustomLogger):
|
|||
data_type="keys",
|
||||
)
|
||||
|
||||
async def _initialize_user_budget_metrics(self):
|
||||
"""
|
||||
Initialize user budget metrics by reusing the generic pagination logic.
|
||||
"""
|
||||
from litellm.proxy._types import LiteLLM_UserTable
|
||||
from litellm.proxy.proxy_server import prisma_client
|
||||
|
||||
if prisma_client is None:
|
||||
verbose_logger.debug(
|
||||
"Prometheus: skipping user metrics initialization, DB not initialized"
|
||||
)
|
||||
return
|
||||
|
||||
async def fetch_users(
|
||||
page_size: int, page: int
|
||||
) -> Tuple[List[LiteLLM_UserTable], Optional[int]]:
|
||||
skip = (page - 1) * page_size
|
||||
users = await prisma_client.db.litellm_usertable.find_many(
|
||||
skip=skip,
|
||||
take=page_size,
|
||||
order={"created_at": "desc"},
|
||||
)
|
||||
total_count = await prisma_client.db.litellm_usertable.count()
|
||||
return users, total_count
|
||||
|
||||
await self._initialize_budget_metrics(
|
||||
data_fetch_function=fetch_users,
|
||||
set_metrics_function=self._set_user_list_budget_metrics,
|
||||
data_type="users",
|
||||
)
|
||||
|
||||
async def initialize_remaining_budget_metrics(self):
|
||||
"""
|
||||
Handler for initializing remaining budget metrics for all teams to avoid metric discrepancies.
|
||||
|
|
@ -2261,11 +2338,12 @@ class PrometheusLogger(CustomLogger):
|
|||
|
||||
async def _initialize_remaining_budget_metrics(self):
|
||||
"""
|
||||
Helper to initialize remaining budget metrics for all teams and API keys.
|
||||
Helper to initialize remaining budget metrics for all teams, API keys, and users.
|
||||
"""
|
||||
verbose_logger.debug("Emitting key, team budget metrics....")
|
||||
verbose_logger.debug("Emitting key, team, user budget metrics....")
|
||||
await self._initialize_team_budget_metrics()
|
||||
await self._initialize_api_key_budget_metrics()
|
||||
await self._initialize_user_budget_metrics()
|
||||
|
||||
async def _set_key_list_budget_metrics(
|
||||
self, keys: List[Union[str, UserAPIKeyAuth]]
|
||||
|
|
@ -2280,6 +2358,11 @@ class PrometheusLogger(CustomLogger):
|
|||
for team in teams:
|
||||
self._set_team_budget_metrics(team)
|
||||
|
||||
async def _set_user_list_budget_metrics(self, users: List[LiteLLM_UserTable]):
|
||||
"""Helper function to set budget metrics for a list of users"""
|
||||
for user in users:
|
||||
self._set_user_budget_metrics(user)
|
||||
|
||||
async def _set_team_budget_metrics_after_api_request(
|
||||
self,
|
||||
user_api_team: Optional[str],
|
||||
|
|
@ -2497,6 +2580,122 @@ class PrometheusLogger(CustomLogger):
|
|||
|
||||
return user_api_key_dict
|
||||
|
||||
async def _set_user_budget_metrics_after_api_request(
|
||||
self,
|
||||
user_id: Optional[str],
|
||||
user_spend: Optional[float],
|
||||
user_max_budget: Optional[float],
|
||||
response_cost: float,
|
||||
):
|
||||
"""
|
||||
Set user budget metrics after an LLM API request
|
||||
|
||||
- Assemble a LiteLLM_UserTable object
|
||||
- looks up user info from db if not available in metadata
|
||||
- Set user budget metrics
|
||||
"""
|
||||
if user_id:
|
||||
user_object = await self._assemble_user_object(
|
||||
user_id=user_id,
|
||||
spend=user_spend,
|
||||
max_budget=user_max_budget,
|
||||
response_cost=response_cost,
|
||||
)
|
||||
|
||||
self._set_user_budget_metrics(user_object)
|
||||
|
||||
async def _assemble_user_object(
|
||||
self,
|
||||
user_id: str,
|
||||
spend: Optional[float],
|
||||
max_budget: Optional[float],
|
||||
response_cost: float,
|
||||
) -> LiteLLM_UserTable:
|
||||
"""
|
||||
Assemble a LiteLLM_UserTable object
|
||||
|
||||
for fields not available in metadata, we fetch from db
|
||||
Fields not available in metadata:
|
||||
- `budget_reset_at`
|
||||
"""
|
||||
from litellm.proxy.auth.auth_checks import get_user_object
|
||||
from litellm.proxy.proxy_server import prisma_client, user_api_key_cache
|
||||
|
||||
_total_user_spend = (spend or 0) + response_cost
|
||||
user_object = LiteLLM_UserTable(
|
||||
user_id=user_id,
|
||||
spend=_total_user_spend,
|
||||
max_budget=max_budget,
|
||||
)
|
||||
try:
|
||||
user_info = await get_user_object(
|
||||
user_id=user_id,
|
||||
prisma_client=prisma_client,
|
||||
user_api_key_cache=user_api_key_cache,
|
||||
user_id_upsert=False,
|
||||
check_db_only=True,
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_logger.debug(
|
||||
f"[Non-Blocking] Prometheus: Error getting user info: {str(e)}"
|
||||
)
|
||||
return user_object
|
||||
|
||||
if user_info:
|
||||
user_object.budget_reset_at = user_info.budget_reset_at
|
||||
|
||||
return user_object
|
||||
|
||||
def _set_user_budget_metrics(
|
||||
self,
|
||||
user: LiteLLM_UserTable,
|
||||
):
|
||||
"""
|
||||
Set user budget metrics for a single user
|
||||
|
||||
- Remaining Budget
|
||||
- Max Budget
|
||||
- Budget Reset At
|
||||
"""
|
||||
enum_values = UserAPIKeyLabelValues(
|
||||
user=user.user_id,
|
||||
)
|
||||
|
||||
_labels = prometheus_label_factory(
|
||||
supported_enum_labels=self.get_labels_for_metric(
|
||||
metric_name="litellm_remaining_user_budget_metric"
|
||||
),
|
||||
enum_values=enum_values,
|
||||
)
|
||||
self.litellm_remaining_user_budget_metric.labels(**_labels).set(
|
||||
self._safe_get_remaining_budget(
|
||||
max_budget=user.max_budget,
|
||||
spend=user.spend,
|
||||
)
|
||||
)
|
||||
|
||||
if user.max_budget is not None:
|
||||
_labels = prometheus_label_factory(
|
||||
supported_enum_labels=self.get_labels_for_metric(
|
||||
metric_name="litellm_user_max_budget_metric"
|
||||
),
|
||||
enum_values=enum_values,
|
||||
)
|
||||
self.litellm_user_max_budget_metric.labels(**_labels).set(user.max_budget)
|
||||
|
||||
if user.budget_reset_at is not None:
|
||||
_labels = prometheus_label_factory(
|
||||
supported_enum_labels=self.get_labels_for_metric(
|
||||
metric_name="litellm_user_budget_remaining_hours_metric"
|
||||
),
|
||||
enum_values=enum_values,
|
||||
)
|
||||
self.litellm_user_budget_remaining_hours_metric.labels(**_labels).set(
|
||||
self._get_remaining_hours_for_budget_reset(
|
||||
budget_reset_at=user.budget_reset_at
|
||||
)
|
||||
)
|
||||
|
||||
def _get_remaining_hours_for_budget_reset(self, budget_reset_at: datetime) -> float:
|
||||
"""
|
||||
Get remaining hours for budget reset
|
||||
|
|
|
|||
292
litellm/integrations/websearch_interception/ARCHITECTURE.md
Normal file
292
litellm/integrations/websearch_interception/ARCHITECTURE.md
Normal file
|
|
@ -0,0 +1,292 @@
|
|||
# WebSearch Interception Architecture
|
||||
|
||||
Server-side WebSearch tool execution for models that don't natively support it (e.g., Bedrock/Claude).
|
||||
|
||||
## How It Works
|
||||
|
||||
User makes **ONE** `litellm.messages.acreate()` call → Gets final answer with search results.
|
||||
The agentic loop happens transparently on the server.
|
||||
|
||||
## LiteLLM Standard Web Search Tool
|
||||
|
||||
LiteLLM defines a standard web search tool format (`litellm_web_search`) that all native provider tools are converted to. This enables consistent interception across providers.
|
||||
|
||||
**Standard Tool Definition** (defined in `tools.py`):
|
||||
```python
|
||||
{
|
||||
"name": "litellm_web_search",
|
||||
"description": "Search the web for information...",
|
||||
"input_schema": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"query": {"type": "string", "description": "The search query"}
|
||||
},
|
||||
"required": ["query"]
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Tool Name Constant**: `LITELLM_WEB_SEARCH_TOOL_NAME = "litellm_web_search"` (defined in `litellm/constants.py`)
|
||||
|
||||
### Supported Tool Formats
|
||||
|
||||
The interception system automatically detects and handles:
|
||||
|
||||
| Tool Format | Example | Provider | Detection Method | Future-Proof |
|
||||
|-------------|---------|----------|------------------|-------------|
|
||||
| **LiteLLM Standard** | `name="litellm_web_search"` | Any | Direct name match | N/A |
|
||||
| **Anthropic Native** | `type="web_search_20250305"` | Bedrock, Claude API | Type prefix: `startswith("web_search_")` | ✅ Yes (web_search_2026, etc.) |
|
||||
| **Claude Code CLI** | `name="web_search"`, `type="web_search_20250305"` | Claude Code | Name + type check | ✅ Yes (version-agnostic) |
|
||||
| **Legacy** | `name="WebSearch"` | Custom | Name match | N/A (backwards compat) |
|
||||
|
||||
**Future Compatibility**: The `startswith("web_search_")` check in `tools.py` automatically supports future Anthropic web search versions.
|
||||
|
||||
### Claude Code CLI Integration
|
||||
|
||||
Claude Code (Anthropic's official CLI) sends web search requests using Anthropic's native tool format:
|
||||
|
||||
```python
|
||||
{
|
||||
"type": "web_search_20250305",
|
||||
"name": "web_search",
|
||||
"max_uses": 8
|
||||
}
|
||||
```
|
||||
|
||||
**What Happens:**
|
||||
1. Claude Code sends native `web_search_20250305` tool to LiteLLM proxy
|
||||
2. LiteLLM intercepts and converts to `litellm_web_search` standard format
|
||||
3. Bedrock receives converted tool (NOT native format)
|
||||
4. Model returns `tool_use` block for `litellm_web_search` (not `server_tool_use`)
|
||||
5. LiteLLM's agentic loop intercepts the `tool_use`
|
||||
6. Executes `litellm.asearch()` using configured provider (Perplexity, Tavily, etc.)
|
||||
7. Returns final answer to Claude Code user
|
||||
|
||||
**Without Interception**: Bedrock would receive native tool → try to execute natively → return `web_search_tool_result_error` with `invalid_tool_input`
|
||||
|
||||
**With Interception**: LiteLLM converts → Bedrock returns tool_use → LiteLLM executes search → Returns final answer ✅
|
||||
|
||||
### Native Tool Conversion
|
||||
|
||||
Native tools are converted to LiteLLM standard format **before** sending to the provider:
|
||||
|
||||
1. **Conversion Point** (`litellm/llms/anthropic/experimental_pass_through/messages/handler.py`):
|
||||
- In `anthropic_messages()` function (lines 60-127)
|
||||
- Runs BEFORE the API request is made
|
||||
- Detects native web search tools using `is_web_search_tool()`
|
||||
- Converts to `litellm_web_search` format using `get_litellm_web_search_tool()`
|
||||
- Prevents provider from executing search natively (avoids `web_search_tool_result_error`)
|
||||
|
||||
2. **Response Detection** (`transformation.py`):
|
||||
- Detects `tool_use` blocks with any web search tool name
|
||||
- Handles: `litellm_web_search`, `WebSearch`, `web_search`
|
||||
- Extracts search queries for execution
|
||||
|
||||
**Example Conversion**:
|
||||
```python
|
||||
# Input (Claude Code's native tool)
|
||||
{
|
||||
"type": "web_search_20250305",
|
||||
"name": "web_search",
|
||||
"max_uses": 8
|
||||
}
|
||||
|
||||
# Output (LiteLLM standard)
|
||||
{
|
||||
"name": "litellm_web_search",
|
||||
"description": "Search the web for information...",
|
||||
"input_schema": {...}
|
||||
}
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Request Flow
|
||||
|
||||
### Without Interception (Client-Side)
|
||||
User manually handles tool execution:
|
||||
1. User calls `litellm.messages.acreate()` → Gets `tool_use` response
|
||||
2. User executes `litellm.asearch()`
|
||||
3. User calls `litellm.messages.acreate()` again with results
|
||||
4. User gets final answer
|
||||
|
||||
**Result**: 2 API calls, manual tool execution
|
||||
|
||||
### With Interception (Server-Side)
|
||||
Server handles tool execution automatically:
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant User
|
||||
participant Messages as litellm.messages.acreate()
|
||||
participant Handler as llm_http_handler.py
|
||||
participant Logger as WebSearchInterceptionLogger
|
||||
participant Router as proxy_server.llm_router
|
||||
participant Search as litellm.asearch()
|
||||
participant Provider as Bedrock API
|
||||
|
||||
User->>Messages: acreate(tools=[WebSearch])
|
||||
Messages->>Handler: async_anthropic_messages_handler()
|
||||
Handler->>Provider: Request
|
||||
Provider-->>Handler: Response (tool_use)
|
||||
Handler->>Logger: async_should_run_agentic_loop()
|
||||
Logger->>Logger: Detect WebSearch tool_use
|
||||
Logger-->>Handler: (True, tools)
|
||||
Handler->>Logger: async_run_agentic_loop(tools)
|
||||
Logger->>Router: Get search_provider from search_tools
|
||||
Router-->>Logger: search_provider
|
||||
Logger->>Search: asearch(query, provider)
|
||||
Search-->>Logger: Search results
|
||||
Logger->>Logger: Build tool_result message
|
||||
Logger->>Messages: acreate() with results
|
||||
Messages->>Provider: Request with search results
|
||||
Provider-->>Messages: Final answer
|
||||
Messages-->>Logger: Final response
|
||||
Logger-->>Handler: Final response
|
||||
Handler-->>User: Final answer (with search results)
|
||||
```
|
||||
|
||||
**Result**: 1 API call from user, server handles agentic loop
|
||||
|
||||
---
|
||||
|
||||
## Key Components
|
||||
|
||||
| Component | File | Purpose |
|
||||
|-----------|------|---------|
|
||||
| **WebSearchInterceptionLogger** | `handler.py` | CustomLogger that implements agentic loop hooks |
|
||||
| **Tool Standardization** | `tools.py` | Standard tool definition, detection, and utilities |
|
||||
| **Tool Name Constant** | `constants.py` | `LITELLM_WEB_SEARCH_TOOL_NAME = "litellm_web_search"` |
|
||||
| **Tool Conversion** | `anthropic/.../ handler.py` | Converts native tools to LiteLLM standard before API call |
|
||||
| **Transformation Logic** | `transformation.py` | Detect tool_use, build tool_result messages, format search responses |
|
||||
| **Agentic Loop Hooks** | `integrations/custom_logger.py` | Base hooks: `async_should_run_agentic_loop()`, `async_run_agentic_loop()` |
|
||||
| **Hook Orchestration** | `llms/custom_httpx/llm_http_handler.py` | `_call_agentic_completion_hooks()` - calls hooks after response |
|
||||
| **Router Search Tools** | `proxy/proxy_server.py` | `llm_router.search_tools` - configured search providers |
|
||||
| **Search Endpoints** | `proxy/search_endpoints/endpoints.py` | Router logic for selecting search provider |
|
||||
|
||||
---
|
||||
|
||||
## Configuration
|
||||
|
||||
```python
|
||||
from litellm.integrations.websearch_interception import (
|
||||
WebSearchInterceptionLogger,
|
||||
get_litellm_web_search_tool,
|
||||
)
|
||||
from litellm.types.utils import LlmProviders
|
||||
|
||||
# Enable for Bedrock with specific search tool
|
||||
litellm.callbacks = [
|
||||
WebSearchInterceptionLogger(
|
||||
enabled_providers=[LlmProviders.BEDROCK],
|
||||
search_tool_name="my-perplexity-tool" # Optional: uses router's first tool if None
|
||||
)
|
||||
]
|
||||
|
||||
# Make request with LiteLLM standard tool (recommended)
|
||||
response = await litellm.messages.acreate(
|
||||
model="bedrock/us.anthropic.claude-sonnet-4-5-20250929-v1:0",
|
||||
messages=[{"role": "user", "content": "What is LiteLLM?"}],
|
||||
tools=[get_litellm_web_search_tool()], # LiteLLM standard
|
||||
max_tokens=1024,
|
||||
stream=True # Auto-converted to non-streaming
|
||||
)
|
||||
|
||||
# OR send native tools - they're auto-converted to LiteLLM standard
|
||||
response = await litellm.messages.acreate(
|
||||
model="bedrock/us.anthropic.claude-sonnet-4-5-20250929-v1:0",
|
||||
messages=[{"role": "user", "content": "What is LiteLLM?"}],
|
||||
tools=[{
|
||||
"type": "web_search_20250305", # Native Anthropic format
|
||||
"name": "web_search",
|
||||
"max_uses": 8
|
||||
}],
|
||||
max_tokens=1024,
|
||||
)
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Streaming Support
|
||||
|
||||
WebSearch interception works transparently with both streaming and non-streaming requests.
|
||||
|
||||
**How streaming is handled:**
|
||||
1. User makes request with `stream=True` and WebSearch tool
|
||||
2. Before API call, `anthropic_messages()` detects WebSearch + interception enabled
|
||||
3. Converts `stream=True` → `stream=False` internally
|
||||
4. Agentic loop executes with non-streaming responses
|
||||
5. Final response returned to user (non-streaming)
|
||||
|
||||
**Why this approach:**
|
||||
- Server-side agentic loops require consuming full responses to detect tool_use
|
||||
- User opts into this behavior by enabling WebSearch interception
|
||||
- Provides seamless experience without client changes
|
||||
|
||||
**Testing:**
|
||||
- **Non-streaming**: `test_websearch_interception_e2e.py`
|
||||
- **Streaming**: `test_websearch_interception_streaming_e2e.py`
|
||||
|
||||
---
|
||||
|
||||
## Search Provider Selection
|
||||
|
||||
1. If `search_tool_name` specified → Look up in `llm_router.search_tools`
|
||||
2. If not found or None → Use first available search tool
|
||||
3. If no router or no tools → Fallback to `perplexity`
|
||||
|
||||
Example router config:
|
||||
```yaml
|
||||
search_tools:
|
||||
- search_tool_name: "my-perplexity-tool"
|
||||
litellm_params:
|
||||
search_provider: "perplexity"
|
||||
- search_tool_name: "my-tavily-tool"
|
||||
litellm_params:
|
||||
search_provider: "tavily"
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Message Flow
|
||||
|
||||
### Initial Request
|
||||
```python
|
||||
messages = [{"role": "user", "content": "What is LiteLLM?"}]
|
||||
tools = [{"name": "WebSearch", ...}]
|
||||
```
|
||||
|
||||
### First API Call (Internal)
|
||||
**Response**: `tool_use` with `name="WebSearch"`, `input={"query": "what is litellm"}`
|
||||
|
||||
### Server Processing
|
||||
1. Logger detects WebSearch tool_use
|
||||
2. Looks up search provider from router
|
||||
3. Executes `litellm.asearch(query="what is litellm", search_provider="perplexity")`
|
||||
4. Gets results: `"Title: LiteLLM Docs\nURL: docs.litellm.ai\n..."`
|
||||
|
||||
### Follow-Up Request (Internal)
|
||||
```python
|
||||
messages = [
|
||||
{"role": "user", "content": "What is LiteLLM?"},
|
||||
{"role": "assistant", "content": [{"type": "tool_use", ...}]},
|
||||
{"role": "user", "content": [{"type": "tool_result", "content": "search results..."}]}
|
||||
]
|
||||
```
|
||||
|
||||
### User Receives
|
||||
```python
|
||||
response.content[0].text
|
||||
# "Based on the search results, LiteLLM is a unified interface..."
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Testing
|
||||
|
||||
**E2E Tests**:
|
||||
- `test_websearch_interception_e2e.py` - Non-streaming real API calls to Bedrock
|
||||
- `test_websearch_interception_streaming_e2e.py` - Streaming real API calls to Bedrock
|
||||
|
||||
**Unit Tests**: `test_websearch_interception.py`
|
||||
Mocked tests for tool detection, provider filtering, edge cases.
|
||||
20
litellm/integrations/websearch_interception/__init__.py
Normal file
20
litellm/integrations/websearch_interception/__init__.py
Normal file
|
|
@ -0,0 +1,20 @@
|
|||
"""
|
||||
WebSearch Interception Module
|
||||
|
||||
Provides server-side WebSearch tool execution for models that don't natively
|
||||
support server-side tool calling (e.g., Bedrock/Claude).
|
||||
"""
|
||||
|
||||
from litellm.integrations.websearch_interception.handler import (
|
||||
WebSearchInterceptionLogger,
|
||||
)
|
||||
from litellm.integrations.websearch_interception.tools import (
|
||||
get_litellm_web_search_tool,
|
||||
is_web_search_tool,
|
||||
)
|
||||
|
||||
__all__ = [
|
||||
"WebSearchInterceptionLogger",
|
||||
"get_litellm_web_search_tool",
|
||||
"is_web_search_tool",
|
||||
]
|
||||
553
litellm/integrations/websearch_interception/handler.py
Normal file
553
litellm/integrations/websearch_interception/handler.py
Normal file
|
|
@ -0,0 +1,553 @@
|
|||
"""
|
||||
WebSearch Interception Handler
|
||||
|
||||
CustomLogger that intercepts WebSearch tool calls for models that don't
|
||||
natively support web search (e.g., Bedrock/Claude) and executes them
|
||||
server-side using litellm router's search tools.
|
||||
"""
|
||||
|
||||
import asyncio
|
||||
from typing import Any, Dict, List, Optional, Tuple, Union, cast
|
||||
|
||||
import litellm
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.anthropic_interface import messages as anthropic_messages
|
||||
from litellm.constants import LITELLM_WEB_SEARCH_TOOL_NAME
|
||||
from litellm.integrations.custom_logger import CustomLogger
|
||||
from litellm.integrations.websearch_interception.tools import (
|
||||
get_litellm_web_search_tool,
|
||||
is_web_search_tool,
|
||||
)
|
||||
from litellm.integrations.websearch_interception.transformation import (
|
||||
WebSearchTransformation,
|
||||
)
|
||||
from litellm.types.integrations.websearch_interception import (
|
||||
WebSearchInterceptionConfig,
|
||||
)
|
||||
from litellm.types.utils import LlmProviders
|
||||
|
||||
|
||||
class WebSearchInterceptionLogger(CustomLogger):
|
||||
"""
|
||||
CustomLogger that intercepts WebSearch tool calls for models that don't
|
||||
natively support web search.
|
||||
|
||||
Implements agentic loop:
|
||||
1. Detects WebSearch tool_use in model response
|
||||
2. Executes litellm.asearch() for each query using router's search tools
|
||||
3. Makes follow-up request with search results
|
||||
4. Returns final response
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
enabled_providers: Optional[List[Union[LlmProviders, str]]] = None,
|
||||
search_tool_name: Optional[str] = None,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
enabled_providers: List of LLM providers to enable interception for.
|
||||
Use LlmProviders enum values (e.g., [LlmProviders.BEDROCK])
|
||||
Default: [LlmProviders.BEDROCK]
|
||||
search_tool_name: Name of search tool configured in router's search_tools.
|
||||
If None, will attempt to use first available search tool.
|
||||
"""
|
||||
super().__init__()
|
||||
# Convert enum values to strings for comparison
|
||||
if enabled_providers is None:
|
||||
self.enabled_providers = [LlmProviders.BEDROCK.value]
|
||||
else:
|
||||
self.enabled_providers = [
|
||||
p.value if isinstance(p, LlmProviders) else p
|
||||
for p in enabled_providers
|
||||
]
|
||||
self.search_tool_name = search_tool_name
|
||||
self._request_has_websearch = False # Track if current request has web search
|
||||
|
||||
async def async_pre_call_deployment_hook(
|
||||
self, kwargs: Dict[str, Any], call_type: Optional[Any]
|
||||
) -> Optional[dict]:
|
||||
"""
|
||||
Pre-call hook to convert native Anthropic web_search tools to regular tools.
|
||||
|
||||
This prevents Bedrock from trying to execute web search server-side (which fails).
|
||||
Instead, we convert it to a regular tool so the model returns tool_use blocks
|
||||
that we can intercept and execute ourselves.
|
||||
"""
|
||||
# Check if this is for an enabled provider
|
||||
custom_llm_provider = kwargs.get("litellm_params", {}).get("custom_llm_provider", "")
|
||||
if custom_llm_provider not in self.enabled_providers:
|
||||
return None
|
||||
|
||||
# Check if request has tools with native web_search
|
||||
tools = kwargs.get("tools")
|
||||
if not tools:
|
||||
return None
|
||||
|
||||
# Check if any tool is a web search tool (native or already LiteLLM standard)
|
||||
has_websearch = any(is_web_search_tool(t) for t in tools)
|
||||
|
||||
if not has_websearch:
|
||||
return None
|
||||
|
||||
verbose_logger.debug(
|
||||
"WebSearchInterception: Converting native web_search tools to LiteLLM standard"
|
||||
)
|
||||
|
||||
# Convert native/custom web_search tools to LiteLLM standard
|
||||
converted_tools = []
|
||||
for tool in tools:
|
||||
if is_web_search_tool(tool):
|
||||
# Convert to LiteLLM standard web search tool
|
||||
converted_tool = get_litellm_web_search_tool()
|
||||
converted_tools.append(converted_tool)
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Converted {tool.get('name', 'unknown')} "
|
||||
f"(type={tool.get('type', 'none')}) to {LITELLM_WEB_SEARCH_TOOL_NAME}"
|
||||
)
|
||||
else:
|
||||
# Keep other tools as-is
|
||||
converted_tools.append(tool)
|
||||
|
||||
# Return modified kwargs with converted tools
|
||||
return {"tools": converted_tools}
|
||||
|
||||
@classmethod
|
||||
def from_config_yaml(
|
||||
cls, config: WebSearchInterceptionConfig
|
||||
) -> "WebSearchInterceptionLogger":
|
||||
"""
|
||||
Initialize WebSearchInterceptionLogger from proxy config.yaml parameters.
|
||||
|
||||
Args:
|
||||
config: Configuration dictionary from litellm_settings.websearch_interception_params
|
||||
|
||||
Returns:
|
||||
Configured WebSearchInterceptionLogger instance
|
||||
|
||||
Example:
|
||||
From proxy_config.yaml:
|
||||
litellm_settings:
|
||||
websearch_interception_params:
|
||||
enabled_providers: ["bedrock"]
|
||||
search_tool_name: "my-perplexity-search"
|
||||
|
||||
Usage:
|
||||
config = litellm_settings.get("websearch_interception_params", {})
|
||||
logger = WebSearchInterceptionLogger.from_config_yaml(config)
|
||||
"""
|
||||
# Extract parameters from config
|
||||
enabled_providers_str = config.get("enabled_providers", None)
|
||||
search_tool_name = config.get("search_tool_name", None)
|
||||
|
||||
# Convert string provider names to LlmProviders enum values
|
||||
enabled_providers: Optional[List[Union[LlmProviders, str]]] = None
|
||||
if enabled_providers_str is not None:
|
||||
enabled_providers = []
|
||||
for provider in enabled_providers_str:
|
||||
try:
|
||||
# Try to convert string to LlmProviders enum
|
||||
provider_enum = LlmProviders(provider)
|
||||
enabled_providers.append(provider_enum)
|
||||
except ValueError:
|
||||
# If conversion fails, keep as string
|
||||
enabled_providers.append(provider)
|
||||
|
||||
return cls(
|
||||
enabled_providers=enabled_providers,
|
||||
search_tool_name=search_tool_name,
|
||||
)
|
||||
|
||||
async def async_pre_request_hook(
|
||||
self, model: str, messages: List[Dict], kwargs: Dict
|
||||
) -> Optional[Dict]:
|
||||
"""
|
||||
Pre-request hook to convert native web search tools to LiteLLM standard.
|
||||
|
||||
This hook is called before the API request is made, allowing us to:
|
||||
1. Detect native web search tools (web_search_20250305, etc.)
|
||||
2. Convert them to LiteLLM standard format (litellm_web_search)
|
||||
3. Convert stream=True to stream=False for interception
|
||||
|
||||
This prevents providers like Bedrock from trying to execute web search
|
||||
natively (which fails), and ensures our agentic loop can intercept tool_use.
|
||||
|
||||
Returns:
|
||||
Modified kwargs dict with converted tools, or None if no modifications needed
|
||||
"""
|
||||
# Check if this request is for an enabled provider
|
||||
custom_llm_provider = kwargs.get("litellm_params", {}).get(
|
||||
"custom_llm_provider", ""
|
||||
)
|
||||
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Pre-request hook called"
|
||||
f" - custom_llm_provider={custom_llm_provider}"
|
||||
f" - enabled_providers={self.enabled_providers}"
|
||||
)
|
||||
|
||||
if custom_llm_provider not in self.enabled_providers:
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Skipping - provider {custom_llm_provider} not in {self.enabled_providers}"
|
||||
)
|
||||
return None
|
||||
|
||||
# Check if request has tools
|
||||
tools = kwargs.get("tools")
|
||||
if not tools:
|
||||
return None
|
||||
|
||||
# Check if any tool is a web search tool
|
||||
has_websearch = any(is_web_search_tool(t) for t in tools)
|
||||
if not has_websearch:
|
||||
return None
|
||||
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Pre-request hook triggered for provider={custom_llm_provider}"
|
||||
)
|
||||
|
||||
# Convert native web search tools to LiteLLM standard
|
||||
converted_tools = []
|
||||
for tool in tools:
|
||||
if is_web_search_tool(tool):
|
||||
standard_tool = get_litellm_web_search_tool()
|
||||
converted_tools.append(standard_tool)
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Converted {tool.get('name', 'unknown')} "
|
||||
f"(type={tool.get('type', 'none')}) to {LITELLM_WEB_SEARCH_TOOL_NAME}"
|
||||
)
|
||||
else:
|
||||
converted_tools.append(tool)
|
||||
|
||||
# Update kwargs with converted tools
|
||||
kwargs["tools"] = converted_tools
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Tools after conversion: {[t.get('name') for t in converted_tools]}"
|
||||
)
|
||||
|
||||
# Convert stream=True to stream=False for WebSearch interception
|
||||
if kwargs.get("stream"):
|
||||
verbose_logger.debug(
|
||||
"WebSearchInterception: Converting stream=True to stream=False"
|
||||
)
|
||||
kwargs["stream"] = False
|
||||
kwargs["_websearch_interception_converted_stream"] = True
|
||||
|
||||
return kwargs
|
||||
|
||||
async def async_should_run_agentic_loop(
|
||||
self,
|
||||
response: Any,
|
||||
model: str,
|
||||
messages: List[Dict],
|
||||
tools: Optional[List[Dict]],
|
||||
stream: bool,
|
||||
custom_llm_provider: str,
|
||||
kwargs: Dict,
|
||||
) -> Tuple[bool, Dict]:
|
||||
"""Check if WebSearch tool interception is needed"""
|
||||
|
||||
verbose_logger.debug(f"WebSearchInterception: Hook called! provider={custom_llm_provider}, stream={stream}")
|
||||
verbose_logger.debug(f"WebSearchInterception: Response type: {type(response)}")
|
||||
|
||||
# Check if provider should be intercepted
|
||||
# Note: custom_llm_provider is already normalized by get_llm_provider()
|
||||
# (e.g., "bedrock/invoke/..." -> "bedrock")
|
||||
if custom_llm_provider not in self.enabled_providers:
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Skipping provider {custom_llm_provider} (not in enabled list: {self.enabled_providers})"
|
||||
)
|
||||
return False, {}
|
||||
|
||||
# Check if tools include any web search tool (LiteLLM standard or native)
|
||||
has_websearch_tool = any(is_web_search_tool(t) for t in (tools or []))
|
||||
if not has_websearch_tool:
|
||||
verbose_logger.debug(
|
||||
"WebSearchInterception: No web search tool in request"
|
||||
)
|
||||
return False, {}
|
||||
|
||||
# Detect WebSearch tool_use in response
|
||||
should_intercept, tool_calls = WebSearchTransformation.transform_request(
|
||||
response=response,
|
||||
stream=stream,
|
||||
)
|
||||
|
||||
if not should_intercept:
|
||||
verbose_logger.debug(
|
||||
"WebSearchInterception: No WebSearch tool_use detected in response"
|
||||
)
|
||||
return False, {}
|
||||
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Detected {len(tool_calls)} WebSearch tool call(s), executing agentic loop"
|
||||
)
|
||||
|
||||
# Return tools dict with tool calls
|
||||
tools_dict = {
|
||||
"tool_calls": tool_calls,
|
||||
"tool_type": "websearch",
|
||||
"provider": custom_llm_provider,
|
||||
}
|
||||
return True, tools_dict
|
||||
|
||||
async def async_run_agentic_loop(
|
||||
self,
|
||||
tools: Dict,
|
||||
model: str,
|
||||
messages: List[Dict],
|
||||
response: Any,
|
||||
anthropic_messages_provider_config: Any,
|
||||
anthropic_messages_optional_request_params: Dict,
|
||||
logging_obj: Any,
|
||||
stream: bool,
|
||||
kwargs: Dict,
|
||||
) -> Any:
|
||||
"""Execute agentic loop with WebSearch execution"""
|
||||
|
||||
tool_calls = tools["tool_calls"]
|
||||
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Executing agentic loop for {len(tool_calls)} search(es)"
|
||||
)
|
||||
|
||||
return await self._execute_agentic_loop(
|
||||
model=model,
|
||||
messages=messages,
|
||||
tool_calls=tool_calls,
|
||||
anthropic_messages_optional_request_params=anthropic_messages_optional_request_params,
|
||||
logging_obj=logging_obj,
|
||||
stream=stream,
|
||||
kwargs=kwargs,
|
||||
)
|
||||
|
||||
async def _execute_agentic_loop(
|
||||
self,
|
||||
model: str,
|
||||
messages: List[Dict],
|
||||
tool_calls: List[Dict],
|
||||
anthropic_messages_optional_request_params: Dict,
|
||||
logging_obj: Any,
|
||||
stream: bool,
|
||||
kwargs: Dict,
|
||||
) -> Any:
|
||||
"""Execute litellm.search() and make follow-up request"""
|
||||
|
||||
# Extract search queries from tool_use blocks
|
||||
search_tasks = []
|
||||
for tool_call in tool_calls:
|
||||
query = tool_call["input"].get("query")
|
||||
if query:
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Queuing search for query='{query}'"
|
||||
)
|
||||
search_tasks.append(self._execute_search(query))
|
||||
else:
|
||||
verbose_logger.warning(
|
||||
f"WebSearchInterception: Tool call {tool_call['id']} has no query"
|
||||
)
|
||||
# Add empty result for tools without query
|
||||
search_tasks.append(self._create_empty_search_result())
|
||||
|
||||
# Execute searches in parallel
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Executing {len(search_tasks)} search(es) in parallel"
|
||||
)
|
||||
search_results = await asyncio.gather(*search_tasks, return_exceptions=True)
|
||||
|
||||
# Handle any exceptions in search results
|
||||
final_search_results: List[str] = []
|
||||
for i, result in enumerate(search_results):
|
||||
if isinstance(result, Exception):
|
||||
verbose_logger.error(
|
||||
f"WebSearchInterception: Search {i} failed with error: {str(result)}"
|
||||
)
|
||||
final_search_results.append(
|
||||
f"Search failed: {str(result)}"
|
||||
)
|
||||
elif isinstance(result, str):
|
||||
# Explicitly cast to str for type checker
|
||||
final_search_results.append(cast(str, result))
|
||||
else:
|
||||
# Should never happen, but handle for type safety
|
||||
verbose_logger.warning(
|
||||
f"WebSearchInterception: Unexpected result type {type(result)} at index {i}"
|
||||
)
|
||||
final_search_results.append(str(result))
|
||||
|
||||
# Build assistant and user messages using transformation
|
||||
assistant_message, user_message = WebSearchTransformation.transform_response(
|
||||
tool_calls=tool_calls,
|
||||
search_results=final_search_results,
|
||||
)
|
||||
|
||||
# Make follow-up request with search results
|
||||
follow_up_messages = messages + [assistant_message, user_message]
|
||||
|
||||
verbose_logger.debug(
|
||||
"WebSearchInterception: Making follow-up request with search results"
|
||||
)
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Follow-up messages count: {len(follow_up_messages)}"
|
||||
)
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Last message (tool_result): {user_message}"
|
||||
)
|
||||
|
||||
# Use anthropic_messages.acreate for follow-up request
|
||||
try:
|
||||
# Extract max_tokens from optional params or kwargs
|
||||
# max_tokens is a required parameter for anthropic_messages.acreate()
|
||||
max_tokens = anthropic_messages_optional_request_params.get(
|
||||
"max_tokens",
|
||||
kwargs.get("max_tokens", 1024) # Default to 1024 if not found
|
||||
)
|
||||
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Using max_tokens={max_tokens} for follow-up request"
|
||||
)
|
||||
|
||||
# Create a copy of optional params without max_tokens (since we pass it explicitly)
|
||||
optional_params_without_max_tokens = {
|
||||
k: v for k, v in anthropic_messages_optional_request_params.items()
|
||||
if k != 'max_tokens'
|
||||
}
|
||||
|
||||
# Get model from logging_obj.model_call_details["agentic_loop_params"]
|
||||
# This preserves the full model name with provider prefix (e.g., "bedrock/invoke/...")
|
||||
full_model_name = model
|
||||
if logging_obj is not None:
|
||||
agentic_params = logging_obj.model_call_details.get("agentic_loop_params", {})
|
||||
full_model_name = agentic_params.get("model", model)
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Using model name: {full_model_name}"
|
||||
)
|
||||
|
||||
final_response = await anthropic_messages.acreate(
|
||||
max_tokens=max_tokens,
|
||||
messages=follow_up_messages,
|
||||
model=full_model_name,
|
||||
**optional_params_without_max_tokens,
|
||||
**kwargs,
|
||||
)
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Follow-up request completed, response type: {type(final_response)}"
|
||||
)
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Final response: {final_response}"
|
||||
)
|
||||
return final_response
|
||||
except Exception as e:
|
||||
verbose_logger.exception(
|
||||
f"WebSearchInterception: Follow-up request failed: {str(e)}"
|
||||
)
|
||||
raise
|
||||
|
||||
async def _execute_search(self, query: str) -> str:
|
||||
"""Execute a single web search using router's search tools"""
|
||||
try:
|
||||
# Import router from proxy_server
|
||||
try:
|
||||
from litellm.proxy.proxy_server import llm_router
|
||||
except ImportError:
|
||||
verbose_logger.warning(
|
||||
"WebSearchInterception: Could not import llm_router from proxy_server, "
|
||||
"falling back to direct litellm.asearch() with perplexity"
|
||||
)
|
||||
llm_router = None
|
||||
|
||||
# Determine search provider from router's search_tools
|
||||
search_provider: Optional[str] = None
|
||||
if llm_router is not None and hasattr(llm_router, "search_tools"):
|
||||
if self.search_tool_name:
|
||||
# Find specific search tool by name
|
||||
matching_tools = [
|
||||
tool for tool in llm_router.search_tools
|
||||
if tool.get("search_tool_name") == self.search_tool_name
|
||||
]
|
||||
if matching_tools:
|
||||
search_tool = matching_tools[0]
|
||||
search_provider = search_tool.get("litellm_params", {}).get("search_provider")
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Found search tool '{self.search_tool_name}' "
|
||||
f"with provider '{search_provider}'"
|
||||
)
|
||||
else:
|
||||
verbose_logger.warning(
|
||||
f"WebSearchInterception: Search tool '{self.search_tool_name}' not found in router, "
|
||||
"falling back to first available or perplexity"
|
||||
)
|
||||
|
||||
# If no specific tool or not found, use first available
|
||||
if not search_provider and llm_router.search_tools:
|
||||
first_tool = llm_router.search_tools[0]
|
||||
search_provider = first_tool.get("litellm_params", {}).get("search_provider")
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Using first available search tool with provider '{search_provider}'"
|
||||
)
|
||||
|
||||
# Fallback to perplexity if no router or no search tools configured
|
||||
if not search_provider:
|
||||
search_provider = "perplexity"
|
||||
verbose_logger.debug(
|
||||
"WebSearchInterception: No search tools configured in router, "
|
||||
f"using default provider '{search_provider}'"
|
||||
)
|
||||
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Executing search for '{query}' using provider '{search_provider}'"
|
||||
)
|
||||
result = await litellm.asearch(
|
||||
query=query, search_provider=search_provider
|
||||
)
|
||||
|
||||
# Format using transformation function
|
||||
search_result_text = WebSearchTransformation.format_search_response(result)
|
||||
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Search completed for '{query}', got {len(search_result_text)} chars"
|
||||
)
|
||||
return search_result_text
|
||||
except Exception as e:
|
||||
verbose_logger.error(
|
||||
f"WebSearchInterception: Search failed for '{query}': {str(e)}"
|
||||
)
|
||||
raise
|
||||
|
||||
async def _create_empty_search_result(self) -> str:
|
||||
"""Create an empty search result for tool calls without queries"""
|
||||
return "No search query provided"
|
||||
|
||||
@staticmethod
|
||||
def initialize_from_proxy_config(
|
||||
litellm_settings: Dict[str, Any],
|
||||
callback_specific_params: Dict[str, Any],
|
||||
) -> "WebSearchInterceptionLogger":
|
||||
"""
|
||||
Static method to initialize WebSearchInterceptionLogger from proxy config.
|
||||
|
||||
Used in callback_utils.py to simplify initialization logic.
|
||||
|
||||
Args:
|
||||
litellm_settings: Dictionary containing litellm_settings from proxy_config.yaml
|
||||
callback_specific_params: Dictionary containing callback-specific parameters
|
||||
|
||||
Returns:
|
||||
Configured WebSearchInterceptionLogger instance
|
||||
|
||||
Example:
|
||||
From callback_utils.py:
|
||||
websearch_obj = WebSearchInterceptionLogger.initialize_from_proxy_config(
|
||||
litellm_settings=litellm_settings,
|
||||
callback_specific_params=callback_specific_params
|
||||
)
|
||||
"""
|
||||
# Get websearch_interception_params from litellm_settings or callback_specific_params
|
||||
websearch_params: WebSearchInterceptionConfig = {}
|
||||
if "websearch_interception_params" in litellm_settings:
|
||||
websearch_params = litellm_settings["websearch_interception_params"]
|
||||
elif "websearch_interception" in callback_specific_params:
|
||||
websearch_params = callback_specific_params["websearch_interception"]
|
||||
|
||||
# Use classmethod to initialize from config
|
||||
return WebSearchInterceptionLogger.from_config_yaml(websearch_params)
|
||||
95
litellm/integrations/websearch_interception/tools.py
Normal file
95
litellm/integrations/websearch_interception/tools.py
Normal file
|
|
@ -0,0 +1,95 @@
|
|||
"""
|
||||
LiteLLM Web Search Tool Definition
|
||||
|
||||
This module defines the standard web search tool used across LiteLLM.
|
||||
Native provider tools (like Anthropic's web_search_20250305) are converted
|
||||
to this format for consistent interception and execution.
|
||||
"""
|
||||
|
||||
from typing import Any, Dict
|
||||
|
||||
from litellm.constants import LITELLM_WEB_SEARCH_TOOL_NAME
|
||||
|
||||
|
||||
def get_litellm_web_search_tool() -> Dict[str, Any]:
|
||||
"""
|
||||
Get the standard LiteLLM web search tool definition.
|
||||
|
||||
This is the canonical tool definition that all native web search tools
|
||||
(like Anthropic's web_search_20250305, Claude Code's web_search, etc.)
|
||||
are converted to for interception.
|
||||
|
||||
Returns:
|
||||
Dict containing the Anthropic-style tool definition with:
|
||||
- name: Tool name
|
||||
- description: What the tool does
|
||||
- input_schema: JSON schema for tool parameters
|
||||
|
||||
Example:
|
||||
>>> tool = get_litellm_web_search_tool()
|
||||
>>> tool['name']
|
||||
'litellm_web_search'
|
||||
"""
|
||||
return {
|
||||
"name": LITELLM_WEB_SEARCH_TOOL_NAME,
|
||||
"description": (
|
||||
"Search the web for information. Use this when you need current "
|
||||
"information or answers to questions that require up-to-date data."
|
||||
),
|
||||
"input_schema": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"query": {
|
||||
"type": "string",
|
||||
"description": "The search query to execute"
|
||||
}
|
||||
},
|
||||
"required": ["query"]
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
def is_web_search_tool(tool: Dict[str, Any]) -> bool:
|
||||
"""
|
||||
Check if a tool is a web search tool (native or LiteLLM standard).
|
||||
|
||||
Detects:
|
||||
- LiteLLM standard: name == "litellm_web_search"
|
||||
- Anthropic native: type starts with "web_search_" (e.g., "web_search_20250305")
|
||||
- Claude Code: name == "web_search" with a type field
|
||||
- Custom: name == "WebSearch" (legacy format)
|
||||
|
||||
Args:
|
||||
tool: Tool dictionary to check
|
||||
|
||||
Returns:
|
||||
True if tool is a web search tool
|
||||
|
||||
Example:
|
||||
>>> is_web_search_tool({"name": "litellm_web_search"})
|
||||
True
|
||||
>>> is_web_search_tool({"type": "web_search_20250305", "name": "web_search"})
|
||||
True
|
||||
>>> is_web_search_tool({"name": "calculator"})
|
||||
False
|
||||
"""
|
||||
tool_name = tool.get("name", "")
|
||||
tool_type = tool.get("type", "")
|
||||
|
||||
# Check for LiteLLM standard tool
|
||||
if tool_name == LITELLM_WEB_SEARCH_TOOL_NAME:
|
||||
return True
|
||||
|
||||
# Check for native Anthropic web_search_* types
|
||||
if tool_type.startswith("web_search_"):
|
||||
return True
|
||||
|
||||
# Check for Claude Code's web_search with a type field
|
||||
if tool_name == "web_search" and tool_type:
|
||||
return True
|
||||
|
||||
# Check for legacy WebSearch format
|
||||
if tool_name == "WebSearch":
|
||||
return True
|
||||
|
||||
return False
|
||||
189
litellm/integrations/websearch_interception/transformation.py
Normal file
189
litellm/integrations/websearch_interception/transformation.py
Normal file
|
|
@ -0,0 +1,189 @@
|
|||
"""
|
||||
WebSearch Tool Transformation
|
||||
|
||||
Transforms between Anthropic tool_use format and LiteLLM search format.
|
||||
"""
|
||||
|
||||
from typing import Any, Dict, List, Tuple
|
||||
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.constants import LITELLM_WEB_SEARCH_TOOL_NAME
|
||||
from litellm.llms.base_llm.search.transformation import SearchResponse
|
||||
|
||||
|
||||
class WebSearchTransformation:
|
||||
"""
|
||||
Transformation class for WebSearch tool interception.
|
||||
|
||||
Handles transformation between:
|
||||
- Anthropic tool_use format → LiteLLM search requests
|
||||
- LiteLLM SearchResponse → Anthropic tool_result format
|
||||
"""
|
||||
|
||||
@staticmethod
|
||||
def transform_request(
|
||||
response: Any,
|
||||
stream: bool,
|
||||
) -> Tuple[bool, List[Dict]]:
|
||||
"""
|
||||
Transform Anthropic response to extract WebSearch tool calls.
|
||||
|
||||
Detects if response contains WebSearch tool_use blocks and extracts
|
||||
the search queries for execution.
|
||||
|
||||
Args:
|
||||
response: Model response (dict or AnthropicMessagesResponse)
|
||||
stream: Whether response is streaming
|
||||
|
||||
Returns:
|
||||
(has_websearch, tool_calls):
|
||||
has_websearch: True if WebSearch tool_use found
|
||||
tool_calls: List of tool_use dicts with id, name, input
|
||||
|
||||
Note:
|
||||
Streaming requests are handled by converting stream=True to stream=False
|
||||
in the WebSearchInterceptionLogger.async_log_pre_api_call hook before
|
||||
the API request is made. This means by the time this method is called,
|
||||
streaming requests have already been converted to non-streaming.
|
||||
"""
|
||||
if stream:
|
||||
# This should not happen in practice since we convert streaming to non-streaming
|
||||
# in async_log_pre_api_call, but keep this check for safety
|
||||
verbose_logger.warning(
|
||||
"WebSearchInterception: Unexpected streaming response, skipping interception"
|
||||
)
|
||||
return False, []
|
||||
|
||||
# Parse non-streaming response
|
||||
return WebSearchTransformation._detect_from_non_streaming_response(response)
|
||||
|
||||
@staticmethod
|
||||
def _detect_from_non_streaming_response(
|
||||
response: Any,
|
||||
) -> Tuple[bool, List[Dict]]:
|
||||
"""Parse non-streaming response for WebSearch tool_use"""
|
||||
|
||||
# Handle both dict and object responses
|
||||
if isinstance(response, dict):
|
||||
content = response.get("content", [])
|
||||
else:
|
||||
if not hasattr(response, "content"):
|
||||
verbose_logger.debug(
|
||||
"WebSearchInterception: Response has no content attribute"
|
||||
)
|
||||
return False, []
|
||||
content = response.content or []
|
||||
|
||||
if not content:
|
||||
verbose_logger.debug(
|
||||
"WebSearchInterception: Response has empty content"
|
||||
)
|
||||
return False, []
|
||||
|
||||
# Find all WebSearch tool_use blocks
|
||||
tool_calls = []
|
||||
for block in content:
|
||||
# Handle both dict and object blocks
|
||||
if isinstance(block, dict):
|
||||
block_type = block.get("type")
|
||||
block_name = block.get("name")
|
||||
block_id = block.get("id")
|
||||
block_input = block.get("input", {})
|
||||
else:
|
||||
block_type = getattr(block, "type", None)
|
||||
block_name = getattr(block, "name", None)
|
||||
block_id = getattr(block, "id", None)
|
||||
block_input = getattr(block, "input", {})
|
||||
|
||||
# Check for LiteLLM standard or legacy web search tools
|
||||
# Handles: litellm_web_search, WebSearch, web_search
|
||||
if block_type == "tool_use" and block_name in (
|
||||
LITELLM_WEB_SEARCH_TOOL_NAME, "WebSearch", "web_search"
|
||||
):
|
||||
# Convert to dict for easier handling
|
||||
tool_call = {
|
||||
"id": block_id,
|
||||
"type": "tool_use",
|
||||
"name": block_name, # Preserve original name
|
||||
"input": block_input,
|
||||
}
|
||||
tool_calls.append(tool_call)
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Found {block_name} tool_use with id={tool_call['id']}"
|
||||
)
|
||||
|
||||
return len(tool_calls) > 0, tool_calls
|
||||
|
||||
@staticmethod
|
||||
def transform_response(
|
||||
tool_calls: List[Dict],
|
||||
search_results: List[str],
|
||||
) -> Tuple[Dict, Dict]:
|
||||
"""
|
||||
Transform LiteLLM search results to Anthropic tool_result format.
|
||||
|
||||
Builds the assistant and user messages needed for the agentic loop
|
||||
follow-up request.
|
||||
|
||||
Args:
|
||||
tool_calls: List of tool_use dicts from transform_request
|
||||
search_results: List of search result strings (one per tool_call)
|
||||
|
||||
Returns:
|
||||
(assistant_message, user_message):
|
||||
assistant_message: Message with tool_use blocks
|
||||
user_message: Message with tool_result blocks
|
||||
"""
|
||||
# Build assistant message with tool_use blocks
|
||||
assistant_message = {
|
||||
"role": "assistant",
|
||||
"content": [
|
||||
{
|
||||
"type": "tool_use",
|
||||
"id": tc["id"],
|
||||
"name": tc["name"],
|
||||
"input": tc["input"],
|
||||
}
|
||||
for tc in tool_calls
|
||||
],
|
||||
}
|
||||
|
||||
# Build user message with tool_result blocks
|
||||
user_message = {
|
||||
"role": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "tool_result",
|
||||
"tool_use_id": tool_calls[i]["id"],
|
||||
"content": search_results[i],
|
||||
}
|
||||
for i in range(len(tool_calls))
|
||||
],
|
||||
}
|
||||
|
||||
return assistant_message, user_message
|
||||
|
||||
@staticmethod
|
||||
def format_search_response(result: SearchResponse) -> str:
|
||||
"""
|
||||
Format SearchResponse as text for tool_result content.
|
||||
|
||||
Args:
|
||||
result: SearchResponse from litellm.asearch()
|
||||
|
||||
Returns:
|
||||
Formatted text with Title, URL, Snippet for each result
|
||||
"""
|
||||
# Convert SearchResponse to string
|
||||
if hasattr(result, "results") and result.results:
|
||||
# Format results as text
|
||||
search_result_text = "\n\n".join(
|
||||
[
|
||||
f"Title: {r.title}\nURL: {r.url}\nSnippet: {r.snippet}"
|
||||
for r in result.results
|
||||
]
|
||||
)
|
||||
else:
|
||||
search_result_text = str(result)
|
||||
|
||||
return search_result_text
|
||||
|
|
@ -3743,10 +3743,10 @@ def _init_custom_logger_compatible_class( # noqa: PLR0915
|
|||
OpenTelemetry,
|
||||
OpenTelemetryConfig,
|
||||
)
|
||||
|
||||
logfire_base_url = os.getenv("LOGFIRE_BASE_URL", "https://logfire-api.pydantic.dev")
|
||||
otel_config = OpenTelemetryConfig(
|
||||
exporter="otlp_http",
|
||||
endpoint="https://logfire-api.pydantic.dev/v1/traces",
|
||||
endpoint = f"{logfire_base_url.rstrip('/')}/v1/traces",
|
||||
headers=f"Authorization={os.getenv('LOGFIRE_TOKEN')}",
|
||||
)
|
||||
for callback in _in_memory_loggers:
|
||||
|
|
@ -4338,6 +4338,38 @@ class StandardLoggingPayloadSetup:
|
|||
|
||||
return messages
|
||||
|
||||
@staticmethod
|
||||
def merge_litellm_metadata(litellm_params: dict) -> dict:
|
||||
"""
|
||||
Merge both litellm_metadata and metadata from litellm_params.
|
||||
|
||||
litellm_metadata contains model-related fields, metadata contains user API key fields.
|
||||
We need both for complete standard logging payload.
|
||||
|
||||
Args:
|
||||
litellm_params: Dictionary containing metadata and litellm_metadata
|
||||
|
||||
Returns:
|
||||
dict: Merged metadata with user API key fields taking precedence
|
||||
"""
|
||||
merged_metadata: dict = {}
|
||||
|
||||
# Start with metadata (user API key fields) - but skip non-serializable objects
|
||||
if litellm_params.get("metadata") and isinstance(litellm_params.get("metadata"), dict):
|
||||
for key, value in litellm_params["metadata"].items():
|
||||
# Skip non-serializable objects like UserAPIKeyAuth
|
||||
if key == "user_api_key_auth":
|
||||
continue
|
||||
merged_metadata[key] = value
|
||||
|
||||
# Then merge litellm_metadata (model-related fields) - this will NOT overwrite existing keys
|
||||
if litellm_params.get("litellm_metadata") and isinstance(litellm_params.get("litellm_metadata"), dict):
|
||||
for key, value in litellm_params["litellm_metadata"].items():
|
||||
if key not in merged_metadata: # Don't overwrite existing keys from metadata
|
||||
merged_metadata[key] = value
|
||||
|
||||
return merged_metadata
|
||||
|
||||
@staticmethod
|
||||
def get_standard_logging_metadata(
|
||||
metadata: Optional[Dict[str, Any]],
|
||||
|
|
@ -4456,7 +4488,7 @@ class StandardLoggingPayloadSetup:
|
|||
|
||||
@staticmethod
|
||||
def get_usage_from_response_obj(
|
||||
response_obj: Optional[Union[dict, BaseModel]], combined_usage_object: Optional[Usage] = None
|
||||
response_obj: Optional[dict], combined_usage_object: Optional[Usage] = None
|
||||
) -> Usage:
|
||||
## BASE CASE ##
|
||||
if combined_usage_object is not None:
|
||||
|
|
@ -4468,32 +4500,27 @@ class StandardLoggingPayloadSetup:
|
|||
total_tokens=0,
|
||||
)
|
||||
|
||||
usage = _safe_extract_usage_from_obj(response_obj)
|
||||
|
||||
if usage is None:
|
||||
usage = response_obj.get("usage", None) or {}
|
||||
if usage is None or (
|
||||
not isinstance(usage, dict) and not isinstance(usage, Usage)
|
||||
):
|
||||
return Usage(
|
||||
prompt_tokens=0,
|
||||
completion_tokens=0,
|
||||
total_tokens=0,
|
||||
)
|
||||
|
||||
if isinstance(usage, Usage):
|
||||
elif isinstance(usage, Usage):
|
||||
return usage
|
||||
|
||||
transformed_usage = _try_transform_response_api_usage(usage)
|
||||
if transformed_usage is not None:
|
||||
return transformed_usage
|
||||
|
||||
if isinstance(usage, dict):
|
||||
created_usage = _try_create_usage_from_dict(usage)
|
||||
if created_usage is not None:
|
||||
return created_usage
|
||||
|
||||
return Usage(
|
||||
prompt_tokens=0,
|
||||
completion_tokens=0,
|
||||
total_tokens=0,
|
||||
)
|
||||
elif isinstance(usage, dict):
|
||||
if ResponseAPILoggingUtils._is_response_api_usage(usage):
|
||||
return (
|
||||
ResponseAPILoggingUtils._transform_response_api_usage_to_chat_usage(
|
||||
usage
|
||||
)
|
||||
)
|
||||
return Usage(**usage)
|
||||
|
||||
raise ValueError(f"usage is required, got={usage} of type {type(usage)}")
|
||||
|
||||
@staticmethod
|
||||
def get_model_cost_information(
|
||||
|
|
@ -4534,18 +4561,13 @@ class StandardLoggingPayloadSetup:
|
|||
|
||||
@staticmethod
|
||||
def get_final_response_obj(
|
||||
response_obj: Union[dict, BaseModel], init_response_obj: Union[Any, BaseModel, dict], kwargs: dict
|
||||
response_obj: dict, init_response_obj: Union[Any, BaseModel, dict], kwargs: dict
|
||||
) -> Optional[Union[dict, str, list]]:
|
||||
"""
|
||||
Get final response object after redacting the message input/output from logging
|
||||
"""
|
||||
if response_obj:
|
||||
if isinstance(response_obj, BaseModel):
|
||||
final_response_obj: Optional[Union[dict, str, list]] = _safe_model_dump(
|
||||
response_obj, default={}
|
||||
)
|
||||
else:
|
||||
final_response_obj = response_obj
|
||||
final_response_obj: Optional[Union[dict, str, list]] = response_obj
|
||||
elif isinstance(init_response_obj, list) or isinstance(init_response_obj, str):
|
||||
final_response_obj = init_response_obj
|
||||
else:
|
||||
|
|
@ -4559,7 +4581,7 @@ class StandardLoggingPayloadSetup:
|
|||
if modified_final_response_obj is not None and isinstance(
|
||||
modified_final_response_obj, BaseModel
|
||||
):
|
||||
final_response_obj = _safe_model_dump(modified_final_response_obj, default={})
|
||||
final_response_obj = modified_final_response_obj.model_dump()
|
||||
else:
|
||||
final_response_obj = modified_final_response_obj
|
||||
|
||||
|
|
@ -4830,125 +4852,6 @@ class StandardLoggingPayloadSetup:
|
|||
return request_tags
|
||||
|
||||
|
||||
def _safe_model_dump(
|
||||
obj: BaseModel, default: Optional[Union[dict, str, list]] = None
|
||||
) -> Union[dict, str, list]:
|
||||
"""
|
||||
Safely call model_dump() on a BaseModel with fallback strategies.
|
||||
|
||||
Args:
|
||||
obj: BaseModel instance to dump
|
||||
default: Default value to return if all strategies fail
|
||||
|
||||
Returns:
|
||||
Dict representation of the BaseModel, or fallback value
|
||||
"""
|
||||
if default is None:
|
||||
default = {}
|
||||
|
||||
try:
|
||||
return obj.model_dump()
|
||||
except (AttributeError, TypeError) as e:
|
||||
verbose_logger.debug(
|
||||
f"Error calling model_dump() on BaseModel: {e}, type: {type(obj)}"
|
||||
)
|
||||
try:
|
||||
if hasattr(obj, "__dict__"):
|
||||
return obj.__dict__
|
||||
else:
|
||||
return str(obj)
|
||||
except Exception:
|
||||
return default
|
||||
|
||||
|
||||
def _safe_get_attribute(
|
||||
obj: Union[dict, BaseModel, Any], attr_name: str, default: Any = None
|
||||
) -> Any:
|
||||
"""
|
||||
Safely get an attribute from a dict or BaseModel object.
|
||||
|
||||
Args:
|
||||
obj: Object to get attribute from (dict, BaseModel, or any object)
|
||||
attr_name: Name of the attribute to get
|
||||
default: Default value to return if attribute doesn't exist
|
||||
|
||||
Returns:
|
||||
Attribute value or default
|
||||
"""
|
||||
try:
|
||||
if isinstance(obj, dict):
|
||||
return obj.get(attr_name, default)
|
||||
else:
|
||||
return getattr(obj, attr_name, default)
|
||||
except (AttributeError, TypeError) as e:
|
||||
verbose_logger.debug(
|
||||
f"Error getting attribute '{attr_name}' from object: {e}, type: {type(obj)}"
|
||||
)
|
||||
return default
|
||||
|
||||
|
||||
def _safe_extract_usage_from_obj(
|
||||
response_obj: Union[dict, BaseModel, Any]
|
||||
) -> Optional[Union[dict, Usage, Any]]:
|
||||
"""
|
||||
Safely extract usage from response_obj (dict or BaseModel).
|
||||
|
||||
Args:
|
||||
response_obj: Response object (dict, BaseModel, or any object)
|
||||
|
||||
Returns:
|
||||
Usage object, dict, or None
|
||||
"""
|
||||
return _safe_get_attribute(response_obj, "usage", None)
|
||||
|
||||
|
||||
def _try_transform_response_api_usage(usage: Any) -> Optional[Usage]:
|
||||
"""
|
||||
Try to transform ResponseAPIUsage to Usage object.
|
||||
|
||||
Args:
|
||||
usage: Usage object (dict, ResponseAPIUsage, or other)
|
||||
|
||||
Returns:
|
||||
Transformed Usage object, or None if transformation fails
|
||||
"""
|
||||
try:
|
||||
if ResponseAPILoggingUtils._is_response_api_usage(usage):
|
||||
return ResponseAPILoggingUtils._transform_response_api_usage_to_chat_usage(usage)
|
||||
except (AttributeError, TypeError, KeyError) as e:
|
||||
verbose_logger.debug(
|
||||
f"Error checking/transforming ResponseAPIUsage: {e}, type: {type(usage)}"
|
||||
)
|
||||
return None
|
||||
|
||||
|
||||
def _try_create_usage_from_dict(usage: dict) -> Optional[Usage]:
|
||||
"""
|
||||
Try to create Usage object from dict.
|
||||
|
||||
Args:
|
||||
usage: Dict containing usage information
|
||||
|
||||
Returns:
|
||||
Usage object, or None if creation fails
|
||||
"""
|
||||
try:
|
||||
return Usage(**usage)
|
||||
except (TypeError, ValueError) as e:
|
||||
# Avoid logging full dict contents, which may include sensitive data
|
||||
try:
|
||||
usage_keys = list(usage.keys())
|
||||
except Exception:
|
||||
usage_keys = None
|
||||
verbose_logger.debug(
|
||||
"Error creating Usage from dict: %s, usage keys: %s, usage type: %s",
|
||||
e,
|
||||
usage_keys,
|
||||
type(usage),
|
||||
)
|
||||
return None
|
||||
|
||||
|
||||
def _get_status_fields(
|
||||
status: StandardLoggingPayloadStatus,
|
||||
guardrail_information: Optional[List[dict]],
|
||||
|
|
@ -4998,21 +4901,17 @@ def _get_status_fields(
|
|||
def _extract_response_obj_and_hidden_params(
|
||||
init_response_obj: Union[Any, BaseModel, dict],
|
||||
original_exception: Optional[Exception],
|
||||
) -> Tuple[Union[dict, BaseModel], Optional[dict]]:
|
||||
|
||||
) -> Tuple[dict, Optional[dict]]:
|
||||
"""Extract response_obj and hidden_params from init_response_obj."""
|
||||
hidden_params: Optional[dict] = None
|
||||
if init_response_obj is None:
|
||||
response_obj: Union[dict, BaseModel] = {}
|
||||
response_obj = {}
|
||||
elif isinstance(init_response_obj, BaseModel):
|
||||
response_obj = init_response_obj
|
||||
hidden_params = _safe_get_attribute(init_response_obj, "_hidden_params", None)
|
||||
response_obj = init_response_obj.model_dump()
|
||||
hidden_params = getattr(init_response_obj, "_hidden_params", None)
|
||||
elif isinstance(init_response_obj, dict):
|
||||
response_obj = init_response_obj
|
||||
else:
|
||||
verbose_logger.debug(
|
||||
f"Unknown init_response_obj type: {type(init_response_obj)}, defaulting to empty dict"
|
||||
)
|
||||
response_obj = {}
|
||||
|
||||
if original_exception is not None and hidden_params is None:
|
||||
|
|
@ -5059,11 +4958,8 @@ def get_standard_logging_object_payload(
|
|||
litellm_params = kwargs.get("litellm_params", {}) or {}
|
||||
proxy_server_request = litellm_params.get("proxy_server_request") or {}
|
||||
|
||||
metadata: dict = (
|
||||
litellm_params.get("litellm_metadata")
|
||||
or litellm_params.get("metadata", None)
|
||||
or {}
|
||||
)
|
||||
# Merge both litellm_metadata and metadata to get complete metadata
|
||||
metadata: dict = StandardLoggingPayloadSetup.merge_litellm_metadata(litellm_params)
|
||||
|
||||
completion_start_time = kwargs.get("completion_start_time", end_time)
|
||||
call_type = kwargs.get("call_type")
|
||||
|
|
@ -5075,10 +4971,7 @@ def get_standard_logging_object_payload(
|
|||
),
|
||||
)
|
||||
|
||||
# Preserve falsy values (0, "", False) if they exist in response_obj
|
||||
id = _safe_get_attribute(response_obj, "id", None)
|
||||
if id is None:
|
||||
id = kwargs.get("litellm_call_id")
|
||||
id = response_obj.get("id", kwargs.get("litellm_call_id"))
|
||||
|
||||
_model_id = metadata.get("model_info", {}).get("id", "")
|
||||
_model_group = metadata.get("model_group", "")
|
||||
|
|
|
|||
|
|
@ -45,7 +45,6 @@ from .common_utils import (
|
|||
infer_content_type_from_url_and_content,
|
||||
is_non_content_values_set,
|
||||
parse_tool_call_arguments,
|
||||
unpack_defs,
|
||||
)
|
||||
from .image_handling import convert_url_to_base64
|
||||
|
||||
|
|
@ -904,11 +903,11 @@ def convert_to_anthropic_image_obj(
|
|||
media_type=media_type,
|
||||
data=base64_data,
|
||||
)
|
||||
except litellm.ImageFetchError:
|
||||
raise
|
||||
except Exception as e:
|
||||
if "Error: Unable to fetch image from URL" in str(e):
|
||||
raise e
|
||||
raise Exception(
|
||||
"""Image url not in expected format. Example Expected input - "image_url": "data:image/jpeg;base64,{base64_image}". Supported formats - ['image/jpeg', 'image/png', 'image/gif', 'image/webp']."""
|
||||
f"""Image url not in expected format. Example Expected input - "image_url": "data:image/jpeg;base64,{{base64_image}}". Supported formats - ['image/jpeg', 'image/png', 'image/gif', 'image/webp']. Error: {str(e)}"""
|
||||
)
|
||||
|
||||
|
||||
|
|
@ -1463,56 +1462,6 @@ def convert_to_gemini_tool_call_invoke(
|
|||
)
|
||||
|
||||
|
||||
def _clean_refs_for_gemini(obj: Any) -> None:
|
||||
"""
|
||||
Recursively clean $defs, $ref, and definitions from a dict for Gemini compatibility.
|
||||
|
||||
Gemini rejects:
|
||||
- $defs sections (even after $ref has been inlined)
|
||||
- Any remaining $ref (circular refs, external URLs)
|
||||
|
||||
This function:
|
||||
1. Removes all $defs/definitions keys
|
||||
2. Replaces any remaining $ref with a placeholder object
|
||||
"""
|
||||
if isinstance(obj, dict):
|
||||
# Remove $defs and definitions at this level
|
||||
obj.pop("$defs", None)
|
||||
obj.pop("definitions", None)
|
||||
|
||||
# Check for and handle remaining $ref (circular or external)
|
||||
if "$ref" in obj:
|
||||
ref_value = obj.pop("$ref")
|
||||
# Replace with a generic object type as placeholder
|
||||
obj["type"] = "object"
|
||||
obj["description"] = f"(schema reference: {ref_value})"
|
||||
|
||||
# Recurse into values
|
||||
for value in obj.values():
|
||||
_clean_refs_for_gemini(value)
|
||||
elif isinstance(obj, list):
|
||||
for item in obj:
|
||||
_clean_refs_for_gemini(item)
|
||||
|
||||
|
||||
def _prepare_response_for_gemini(response_data: dict) -> dict:
|
||||
"""
|
||||
Prepare a tool response dict for Gemini by inlining $ref and removing $defs.
|
||||
|
||||
Gemini rejects JSON schemas with $defs/$ref in function_response content.
|
||||
This function applies unpack_defs to inline references, then cleans up
|
||||
any remaining $defs sections and unresolved $refs (circular or external).
|
||||
|
||||
Returns a new dict (does not mutate the input).
|
||||
"""
|
||||
import copy
|
||||
|
||||
result = copy.deepcopy(response_data)
|
||||
unpack_defs(result, {})
|
||||
_clean_refs_for_gemini(result)
|
||||
return result
|
||||
|
||||
|
||||
def convert_to_gemini_tool_call_result(
|
||||
message: Union[ChatCompletionToolMessage, ChatCompletionFunctionMessage],
|
||||
last_message_with_tool_calls: Optional[dict],
|
||||
|
|
@ -1606,8 +1555,6 @@ def convert_to_gemini_tool_call_result(
|
|||
# For Computer Use, the response should contain structured data like {"url": "..."}
|
||||
response_data: dict
|
||||
try:
|
||||
import json
|
||||
|
||||
if content_str.strip().startswith("{") or content_str.strip().startswith("["):
|
||||
# Try to parse as JSON (for Computer Use structured responses)
|
||||
parsed = json.loads(content_str)
|
||||
|
|
@ -1621,11 +1568,6 @@ def convert_to_gemini_tool_call_result(
|
|||
# Not valid JSON, wrap in content field
|
||||
response_data = {"content": content_str}
|
||||
|
||||
# Gemini rejects JSON schemas with $defs/$ref in function_response content.
|
||||
# Inline $refs and clean up for Gemini compatibility.
|
||||
if isinstance(response_data, dict):
|
||||
response_data = _prepare_response_for_gemini(response_data)
|
||||
|
||||
# We can't determine from openai message format whether it's a successful or
|
||||
# error call result so default to the successful result template
|
||||
_function_response = VertexFunctionResponse(
|
||||
|
|
@ -1728,7 +1670,7 @@ def convert_to_anthropic_tool_result(
|
|||
anthropic_content_element=_anthropic_image_param,
|
||||
original_content_element=content,
|
||||
)
|
||||
anthropic_content_list.append(_anthropic_image_param)
|
||||
anthropic_content_list.append(cast(AnthropicMessagesImageParam, _anthropic_image_param))
|
||||
|
||||
anthropic_content = anthropic_content_list
|
||||
anthropic_tool_result: Optional[AnthropicMessagesToolResultParam] = None
|
||||
|
|
|
|||
|
|
@ -9,6 +9,7 @@ from httpx import Response
|
|||
import litellm
|
||||
from litellm import verbose_logger
|
||||
from litellm.caching.caching import InMemoryCache
|
||||
from litellm.constants import MAX_IMAGE_URL_DOWNLOAD_SIZE_MB
|
||||
|
||||
MAX_IMGS_IN_MEMORY = 10
|
||||
|
||||
|
|
@ -21,7 +22,25 @@ def _process_image_response(response: Response, url: str) -> str:
|
|||
f"Error: Unable to fetch image from URL. Status code: {response.status_code}, url={url}"
|
||||
)
|
||||
|
||||
# Check size before downloading if Content-Length header is present
|
||||
content_length = response.headers.get("Content-Length")
|
||||
if content_length is not None:
|
||||
size_mb = int(content_length) / (1024 * 1024)
|
||||
if size_mb > MAX_IMAGE_URL_DOWNLOAD_SIZE_MB:
|
||||
raise litellm.ImageFetchError(
|
||||
f"Error: Image size ({size_mb:.2f}MB) exceeds maximum allowed size ({MAX_IMAGE_URL_DOWNLOAD_SIZE_MB}MB). url={url}"
|
||||
)
|
||||
|
||||
image_bytes = response.content
|
||||
|
||||
# Check actual size after download if Content-Length was not available
|
||||
if content_length is None:
|
||||
size_mb = len(image_bytes) / (1024 * 1024)
|
||||
if size_mb > MAX_IMAGE_URL_DOWNLOAD_SIZE_MB:
|
||||
raise litellm.ImageFetchError(
|
||||
f"Error: Image size ({size_mb:.2f}MB) exceeds maximum allowed size ({MAX_IMAGE_URL_DOWNLOAD_SIZE_MB}MB). url={url}"
|
||||
)
|
||||
|
||||
base64_image = base64.b64encode(image_bytes).decode("utf-8")
|
||||
|
||||
image_type = response.headers.get("Content-Type")
|
||||
|
|
@ -48,6 +67,12 @@ def _process_image_response(response: Response, url: str) -> str:
|
|||
|
||||
|
||||
async def async_convert_url_to_base64(url: str) -> str:
|
||||
# If MAX_IMAGE_URL_DOWNLOAD_SIZE_MB is 0, block all image downloads
|
||||
if MAX_IMAGE_URL_DOWNLOAD_SIZE_MB == 0:
|
||||
raise litellm.ImageFetchError(
|
||||
f"Error: Image URL download is disabled (MAX_IMAGE_URL_DOWNLOAD_SIZE_MB=0). url={url}"
|
||||
)
|
||||
|
||||
cached_result = in_memory_cache.get_cache(url)
|
||||
if cached_result:
|
||||
return cached_result
|
||||
|
|
@ -67,6 +92,12 @@ async def async_convert_url_to_base64(url: str) -> str:
|
|||
|
||||
|
||||
def convert_url_to_base64(url: str) -> str:
|
||||
# If MAX_IMAGE_URL_DOWNLOAD_SIZE_MB is 0, block all image downloads
|
||||
if MAX_IMAGE_URL_DOWNLOAD_SIZE_MB == 0:
|
||||
raise litellm.ImageFetchError(
|
||||
f"Error: Image URL download is disabled (MAX_IMAGE_URL_DOWNLOAD_SIZE_MB=0). url={url}"
|
||||
)
|
||||
|
||||
cached_result = in_memory_cache.get_cache(url)
|
||||
if cached_result:
|
||||
return cached_result
|
||||
|
|
|
|||
|
|
@ -132,7 +132,7 @@ class ChunkProcessor:
|
|||
)
|
||||
return response
|
||||
|
||||
def get_combined_tool_content(
|
||||
def get_combined_tool_content( # noqa: PLR0915
|
||||
self, tool_call_chunks: List[Dict[str, Any]]
|
||||
) -> List[ChatCompletionMessageToolCall]:
|
||||
tool_calls_list: List[ChatCompletionMessageToolCall] = []
|
||||
|
|
@ -147,10 +147,26 @@ class ChunkProcessor:
|
|||
tool_calls = delta.get("tool_calls", [])
|
||||
|
||||
for tool_call in tool_calls:
|
||||
if not tool_call or not hasattr(tool_call, "function"):
|
||||
# Handle both dict and object formats
|
||||
if not tool_call:
|
||||
continue
|
||||
|
||||
# Check if tool_call has function (either as attribute or dict key)
|
||||
has_function = False
|
||||
if isinstance(tool_call, dict):
|
||||
has_function = "function" in tool_call and tool_call["function"] is not None
|
||||
else:
|
||||
has_function = hasattr(tool_call, "function") and tool_call.function is not None
|
||||
|
||||
if not has_function:
|
||||
continue
|
||||
|
||||
index = getattr(tool_call, "index", 0)
|
||||
# Get index (handle both dict and object)
|
||||
if isinstance(tool_call, dict):
|
||||
index = tool_call.get("index", 0)
|
||||
else:
|
||||
index = getattr(tool_call, "index", 0)
|
||||
|
||||
if index not in tool_call_map:
|
||||
tool_call_map[index] = {
|
||||
"id": None,
|
||||
|
|
@ -160,30 +176,56 @@ class ChunkProcessor:
|
|||
"provider_specific_fields": None,
|
||||
}
|
||||
|
||||
if hasattr(tool_call, "id") and tool_call.id:
|
||||
tool_call_map[index]["id"] = tool_call.id
|
||||
if hasattr(tool_call, "type") and tool_call.type:
|
||||
tool_call_map[index]["type"] = tool_call.type
|
||||
if hasattr(tool_call, "function"):
|
||||
if (
|
||||
hasattr(tool_call.function, "name")
|
||||
and tool_call.function.name
|
||||
):
|
||||
tool_call_map[index]["name"] = tool_call.function.name
|
||||
if (
|
||||
hasattr(tool_call.function, "arguments")
|
||||
and tool_call.function.arguments
|
||||
):
|
||||
tool_call_map[index]["arguments"].append(
|
||||
tool_call.function.arguments
|
||||
)
|
||||
# Extract id, type, and function data (handle both dict and object)
|
||||
if isinstance(tool_call, dict):
|
||||
if tool_call.get("id"):
|
||||
tool_call_map[index]["id"] = tool_call["id"]
|
||||
if tool_call.get("type"):
|
||||
tool_call_map[index]["type"] = tool_call["type"]
|
||||
|
||||
function = tool_call.get("function", {})
|
||||
if isinstance(function, dict):
|
||||
if function.get("name"):
|
||||
tool_call_map[index]["name"] = function["name"]
|
||||
if function.get("arguments"):
|
||||
tool_call_map[index]["arguments"].append(function["arguments"])
|
||||
else:
|
||||
# function is an object
|
||||
if hasattr(function, "name") and function.name:
|
||||
tool_call_map[index]["name"] = function.name
|
||||
if hasattr(function, "arguments") and function.arguments:
|
||||
tool_call_map[index]["arguments"].append(function.arguments)
|
||||
else:
|
||||
# tool_call is an object
|
||||
if hasattr(tool_call, "id") and tool_call.id:
|
||||
tool_call_map[index]["id"] = tool_call.id
|
||||
if hasattr(tool_call, "type") and tool_call.type:
|
||||
tool_call_map[index]["type"] = tool_call.type
|
||||
if hasattr(tool_call, "function"):
|
||||
if (
|
||||
hasattr(tool_call.function, "name")
|
||||
and tool_call.function.name
|
||||
):
|
||||
tool_call_map[index]["name"] = tool_call.function.name
|
||||
if (
|
||||
hasattr(tool_call.function, "arguments")
|
||||
and tool_call.function.arguments
|
||||
):
|
||||
tool_call_map[index]["arguments"].append(
|
||||
tool_call.function.arguments
|
||||
)
|
||||
|
||||
# Preserve provider_specific_fields from streaming chunks
|
||||
provider_fields = None
|
||||
if hasattr(tool_call, "provider_specific_fields") and tool_call.provider_specific_fields:
|
||||
provider_fields = tool_call.provider_specific_fields
|
||||
elif hasattr(tool_call, "function") and hasattr(tool_call.function, "provider_specific_fields") and tool_call.function.provider_specific_fields:
|
||||
provider_fields = tool_call.function.provider_specific_fields
|
||||
if isinstance(tool_call, dict):
|
||||
provider_fields = tool_call.get("provider_specific_fields")
|
||||
if not provider_fields and isinstance(tool_call.get("function"), dict):
|
||||
provider_fields = tool_call["function"].get("provider_specific_fields")
|
||||
else:
|
||||
if hasattr(tool_call, "provider_specific_fields") and tool_call.provider_specific_fields:
|
||||
provider_fields = tool_call.provider_specific_fields
|
||||
elif hasattr(tool_call, "function") and hasattr(tool_call.function, "provider_specific_fields") and tool_call.function.provider_specific_fields:
|
||||
provider_fields = tool_call.function.provider_specific_fields
|
||||
|
||||
if provider_fields:
|
||||
# Merge provider_specific_fields if multiple chunks have them
|
||||
|
|
@ -222,6 +264,7 @@ class ChunkProcessor:
|
|||
|
||||
return tool_calls_list
|
||||
|
||||
|
||||
def get_combined_function_call_content(
|
||||
self, function_call_chunks: List[Dict[str, Any]]
|
||||
) -> FunctionCall:
|
||||
|
|
|
|||
|
|
@ -0,0 +1,246 @@
|
|||
"""
|
||||
Fake Streaming Iterator for Anthropic Messages
|
||||
|
||||
This module provides a fake streaming iterator that converts non-streaming
|
||||
Anthropic Messages responses into proper streaming format.
|
||||
|
||||
Used when WebSearch interception converts stream=True to stream=False but
|
||||
the LLM doesn't make a tool call, and we need to return a stream to the user.
|
||||
"""
|
||||
|
||||
import json
|
||||
from typing import Any, Dict, List, cast
|
||||
|
||||
from litellm.types.llms.anthropic_messages.anthropic_response import (
|
||||
AnthropicMessagesResponse,
|
||||
)
|
||||
|
||||
|
||||
class FakeAnthropicMessagesStreamIterator:
|
||||
"""
|
||||
Fake streaming iterator for Anthropic Messages responses.
|
||||
|
||||
Used when we need to convert a non-streaming response to a streaming format,
|
||||
such as when WebSearch interception converts stream=True to stream=False but
|
||||
the LLM doesn't make a tool call.
|
||||
|
||||
This creates a proper Anthropic-style streaming response with multiple events:
|
||||
- message_start
|
||||
- content_block_start (for each content block)
|
||||
- content_block_delta (for text content, chunked)
|
||||
- content_block_stop
|
||||
- message_delta (for usage)
|
||||
- message_stop
|
||||
"""
|
||||
|
||||
def __init__(self, response: AnthropicMessagesResponse):
|
||||
self.response = response
|
||||
self.chunks = self._create_streaming_chunks()
|
||||
self.current_index = 0
|
||||
|
||||
def _create_streaming_chunks(self) -> List[bytes]:
|
||||
"""Convert the non-streaming response to streaming chunks"""
|
||||
chunks = []
|
||||
|
||||
# Cast response to dict for easier access
|
||||
response_dict = cast(Dict[str, Any], self.response)
|
||||
|
||||
# 1. message_start event
|
||||
usage = response_dict.get("usage", {})
|
||||
message_start = {
|
||||
"type": "message_start",
|
||||
"message": {
|
||||
"id": response_dict.get("id"),
|
||||
"type": "message",
|
||||
"role": response_dict.get("role", "assistant"),
|
||||
"model": response_dict.get("model"),
|
||||
"content": [],
|
||||
"stop_reason": None,
|
||||
"stop_sequence": None,
|
||||
"usage": {
|
||||
"input_tokens": usage.get("input_tokens", 0) if usage else 0,
|
||||
"output_tokens": 0
|
||||
}
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: message_start\ndata: {json.dumps(message_start)}\n\n".encode())
|
||||
|
||||
# 2-4. For each content block, send start/delta/stop events
|
||||
content_blocks = response_dict.get("content", [])
|
||||
if content_blocks:
|
||||
for index, block in enumerate(content_blocks):
|
||||
# Cast block to dict for easier access
|
||||
block_dict = cast(Dict[str, Any], block)
|
||||
block_type = block_dict.get("type")
|
||||
|
||||
if block_type == "text":
|
||||
# content_block_start
|
||||
content_block_start = {
|
||||
"type": "content_block_start",
|
||||
"index": index,
|
||||
"content_block": {
|
||||
"type": "text",
|
||||
"text": ""
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_start\ndata: {json.dumps(content_block_start)}\n\n".encode())
|
||||
|
||||
# content_block_delta (send full text as one delta for simplicity)
|
||||
text = block_dict.get("text", "")
|
||||
content_block_delta = {
|
||||
"type": "content_block_delta",
|
||||
"index": index,
|
||||
"delta": {
|
||||
"type": "text_delta",
|
||||
"text": text
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_delta\ndata: {json.dumps(content_block_delta)}\n\n".encode())
|
||||
|
||||
# content_block_stop
|
||||
content_block_stop = {
|
||||
"type": "content_block_stop",
|
||||
"index": index
|
||||
}
|
||||
chunks.append(f"event: content_block_stop\ndata: {json.dumps(content_block_stop)}\n\n".encode())
|
||||
|
||||
elif block_type == "thinking":
|
||||
# content_block_start for thinking
|
||||
content_block_start = {
|
||||
"type": "content_block_start",
|
||||
"index": index,
|
||||
"content_block": {
|
||||
"type": "thinking",
|
||||
"thinking": "",
|
||||
"signature": ""
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_start\ndata: {json.dumps(content_block_start)}\n\n".encode())
|
||||
|
||||
# content_block_delta for thinking text
|
||||
thinking_text = block_dict.get("thinking", "")
|
||||
if thinking_text:
|
||||
content_block_delta = {
|
||||
"type": "content_block_delta",
|
||||
"index": index,
|
||||
"delta": {
|
||||
"type": "thinking_delta",
|
||||
"thinking": thinking_text
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_delta\ndata: {json.dumps(content_block_delta)}\n\n".encode())
|
||||
|
||||
# content_block_delta for signature (if present)
|
||||
signature = block_dict.get("signature", "")
|
||||
if signature:
|
||||
signature_delta = {
|
||||
"type": "content_block_delta",
|
||||
"index": index,
|
||||
"delta": {
|
||||
"type": "signature_delta",
|
||||
"signature": signature
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_delta\ndata: {json.dumps(signature_delta)}\n\n".encode())
|
||||
|
||||
# content_block_stop
|
||||
content_block_stop = {
|
||||
"type": "content_block_stop",
|
||||
"index": index
|
||||
}
|
||||
chunks.append(f"event: content_block_stop\ndata: {json.dumps(content_block_stop)}\n\n".encode())
|
||||
|
||||
elif block_type == "redacted_thinking":
|
||||
# content_block_start for redacted_thinking
|
||||
content_block_start = {
|
||||
"type": "content_block_start",
|
||||
"index": index,
|
||||
"content_block": {
|
||||
"type": "redacted_thinking"
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_start\ndata: {json.dumps(content_block_start)}\n\n".encode())
|
||||
|
||||
# content_block_stop (no delta for redacted thinking)
|
||||
content_block_stop = {
|
||||
"type": "content_block_stop",
|
||||
"index": index
|
||||
}
|
||||
chunks.append(f"event: content_block_stop\ndata: {json.dumps(content_block_stop)}\n\n".encode())
|
||||
|
||||
elif block_type == "tool_use":
|
||||
# content_block_start
|
||||
content_block_start = {
|
||||
"type": "content_block_start",
|
||||
"index": index,
|
||||
"content_block": {
|
||||
"type": "tool_use",
|
||||
"id": block_dict.get("id"),
|
||||
"name": block_dict.get("name"),
|
||||
"input": {}
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_start\ndata: {json.dumps(content_block_start)}\n\n".encode())
|
||||
|
||||
# content_block_delta (send input as JSON delta)
|
||||
input_data = block_dict.get("input", {})
|
||||
content_block_delta = {
|
||||
"type": "content_block_delta",
|
||||
"index": index,
|
||||
"delta": {
|
||||
"type": "input_json_delta",
|
||||
"partial_json": json.dumps(input_data)
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_delta\ndata: {json.dumps(content_block_delta)}\n\n".encode())
|
||||
|
||||
# content_block_stop
|
||||
content_block_stop = {
|
||||
"type": "content_block_stop",
|
||||
"index": index
|
||||
}
|
||||
chunks.append(f"event: content_block_stop\ndata: {json.dumps(content_block_stop)}\n\n".encode())
|
||||
|
||||
# 5. message_delta event (with final usage and stop_reason)
|
||||
message_delta = {
|
||||
"type": "message_delta",
|
||||
"delta": {
|
||||
"stop_reason": response_dict.get("stop_reason"),
|
||||
"stop_sequence": response_dict.get("stop_sequence")
|
||||
},
|
||||
"usage": {
|
||||
"output_tokens": usage.get("output_tokens", 0) if usage else 0
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: message_delta\ndata: {json.dumps(message_delta)}\n\n".encode())
|
||||
|
||||
# 6. message_stop event
|
||||
message_stop = {
|
||||
"type": "message_stop",
|
||||
"usage": usage if usage else {}
|
||||
}
|
||||
chunks.append(f"event: message_stop\ndata: {json.dumps(message_stop)}\n\n".encode())
|
||||
|
||||
return chunks
|
||||
|
||||
def __aiter__(self):
|
||||
return self
|
||||
|
||||
async def __anext__(self):
|
||||
if self.current_index >= len(self.chunks):
|
||||
raise StopAsyncIteration
|
||||
|
||||
chunk = self.chunks[self.current_index]
|
||||
self.current_index += 1
|
||||
return chunk
|
||||
|
||||
def __iter__(self):
|
||||
return self
|
||||
|
||||
def __next__(self):
|
||||
if self.current_index >= len(self.chunks):
|
||||
raise StopIteration
|
||||
|
||||
chunk = self.chunks[self.current_index]
|
||||
self.current_index += 1
|
||||
return chunk
|
||||
|
|
@ -33,6 +33,70 @@ base_llm_http_handler = BaseLLMHTTPHandler()
|
|||
#################################################
|
||||
|
||||
|
||||
async def _execute_pre_request_hooks(
|
||||
model: str,
|
||||
messages: List[Dict],
|
||||
tools: Optional[List[Dict]],
|
||||
stream: Optional[bool],
|
||||
custom_llm_provider: Optional[str],
|
||||
**kwargs,
|
||||
) -> Dict:
|
||||
"""
|
||||
Execute pre-request hooks from CustomLogger callbacks.
|
||||
|
||||
Allows CustomLoggers to modify request parameters before the API call.
|
||||
Used for WebSearch tool conversion, stream modification, etc.
|
||||
|
||||
Args:
|
||||
model: Model name
|
||||
messages: List of messages
|
||||
tools: Optional tools list
|
||||
stream: Optional stream flag
|
||||
custom_llm_provider: Provider name (if not set, will be extracted from model)
|
||||
**kwargs: Additional request parameters
|
||||
|
||||
Returns:
|
||||
Dict containing all (potentially modified) request parameters including tools, stream
|
||||
"""
|
||||
# If custom_llm_provider not provided, extract from model
|
||||
if not custom_llm_provider:
|
||||
try:
|
||||
_, custom_llm_provider, _, _ = litellm.get_llm_provider(model=model)
|
||||
except Exception:
|
||||
# If extraction fails, continue without provider
|
||||
pass
|
||||
|
||||
# Build complete request kwargs dict
|
||||
request_kwargs = {
|
||||
"tools": tools,
|
||||
"stream": stream,
|
||||
"litellm_params": {
|
||||
"custom_llm_provider": custom_llm_provider,
|
||||
},
|
||||
**kwargs,
|
||||
}
|
||||
|
||||
if not litellm.callbacks:
|
||||
return request_kwargs
|
||||
|
||||
from litellm.integrations.custom_logger import CustomLogger as _CustomLogger
|
||||
|
||||
for callback in litellm.callbacks:
|
||||
if not isinstance(callback, _CustomLogger):
|
||||
continue
|
||||
|
||||
# Call the pre-request hook
|
||||
modified_kwargs = await callback.async_pre_request_hook(
|
||||
model, messages, request_kwargs
|
||||
)
|
||||
|
||||
# If hook returned modified kwargs, use them
|
||||
if modified_kwargs is not None:
|
||||
request_kwargs = modified_kwargs
|
||||
|
||||
return request_kwargs
|
||||
|
||||
|
||||
@client
|
||||
async def anthropic_messages(
|
||||
max_tokens: int,
|
||||
|
|
@ -57,7 +121,24 @@ async def anthropic_messages(
|
|||
"""
|
||||
Async: Make llm api request in Anthropic /messages API spec
|
||||
"""
|
||||
local_vars = locals()
|
||||
# Execute pre-request hooks to allow CustomLoggers to modify request
|
||||
request_kwargs = await _execute_pre_request_hooks(
|
||||
model=model,
|
||||
messages=messages,
|
||||
tools=tools,
|
||||
stream=stream,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
# Extract modified parameters
|
||||
tools = request_kwargs.pop("tools", tools)
|
||||
stream = request_kwargs.pop("stream", stream)
|
||||
# Remove litellm_params from kwargs (only needed for hooks)
|
||||
request_kwargs.pop("litellm_params", None)
|
||||
# Merge back any other modifications
|
||||
kwargs.update(request_kwargs)
|
||||
|
||||
loop = asyncio.get_event_loop()
|
||||
kwargs["is_async"] = True
|
||||
|
||||
|
|
@ -145,6 +226,10 @@ def anthropic_messages_handler(
|
|||
# Use provided client or create a new one
|
||||
litellm_logging_obj: LiteLLMLoggingObj = kwargs.get("litellm_logging_obj") # type: ignore
|
||||
|
||||
# Store original model name before get_llm_provider strips the provider prefix
|
||||
# This is needed by agentic hooks (e.g., websearch_interception) to make follow-up requests
|
||||
original_model = model
|
||||
|
||||
litellm_params = GenericLiteLLMParams(
|
||||
**kwargs,
|
||||
api_key=api_key,
|
||||
|
|
@ -162,6 +247,19 @@ def anthropic_messages_handler(
|
|||
api_base=litellm_params.api_base,
|
||||
api_key=litellm_params.api_key,
|
||||
)
|
||||
|
||||
# Store agentic loop params in logging object for agentic hooks
|
||||
# This provides original request context needed for follow-up calls
|
||||
if litellm_logging_obj is not None:
|
||||
litellm_logging_obj.model_call_details["agentic_loop_params"] = {
|
||||
"model": original_model,
|
||||
"custom_llm_provider": custom_llm_provider,
|
||||
}
|
||||
|
||||
# Check if stream was converted for WebSearch interception
|
||||
# This is set in the async wrapper above when stream=True is converted to stream=False
|
||||
if kwargs.get("_websearch_interception_converted_stream", False):
|
||||
litellm_logging_obj.model_call_details["websearch_interception_converted_stream"] = True
|
||||
|
||||
if litellm_params.mock_response and isinstance(litellm_params.mock_response, str):
|
||||
|
||||
|
|
|
|||
|
|
@ -2,7 +2,8 @@ from typing import Any, AsyncIterator, Dict, List, Optional, Tuple
|
|||
|
||||
import httpx
|
||||
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj, verbose_logger
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj
|
||||
from litellm.litellm_core_utils.litellm_logging import verbose_logger
|
||||
from litellm.llms.base_llm.anthropic_messages.transformation import (
|
||||
BaseAnthropicMessagesConfig,
|
||||
)
|
||||
|
|
@ -13,9 +14,10 @@ from litellm.types.llms.anthropic import (
|
|||
from litellm.types.llms.anthropic_messages.anthropic_response import (
|
||||
AnthropicMessagesResponse,
|
||||
)
|
||||
from litellm.types.llms.anthropic_tool_search import get_tool_search_beta_header
|
||||
from litellm.types.router import GenericLiteLLMParams
|
||||
|
||||
from ...common_utils import AnthropicError
|
||||
from ...common_utils import AnthropicError, AnthropicModelInfo
|
||||
|
||||
DEFAULT_ANTHROPIC_API_BASE = "https://api.anthropic.com"
|
||||
DEFAULT_ANTHROPIC_API_VERSION = "2023-06-01"
|
||||
|
|
@ -75,9 +77,9 @@ class AnthropicMessagesConfig(BaseAnthropicMessagesConfig):
|
|||
if "content-type" not in headers:
|
||||
headers["content-type"] = "application/json"
|
||||
|
||||
headers = self._update_headers_with_optional_anthropic_beta(
|
||||
headers = self._update_headers_with_anthropic_beta(
|
||||
headers=headers,
|
||||
context_management=optional_params.get("context_management"),
|
||||
optional_params=optional_params,
|
||||
)
|
||||
|
||||
return headers, api_base
|
||||
|
|
@ -153,16 +155,44 @@ class AnthropicMessagesConfig(BaseAnthropicMessagesConfig):
|
|||
)
|
||||
|
||||
@staticmethod
|
||||
def _update_headers_with_optional_anthropic_beta(
|
||||
headers: dict, context_management: Optional[Dict]
|
||||
def _update_headers_with_anthropic_beta(
|
||||
headers: dict,
|
||||
optional_params: dict,
|
||||
custom_llm_provider: str = "anthropic",
|
||||
) -> dict:
|
||||
if context_management is None:
|
||||
return headers
|
||||
|
||||
"""
|
||||
Auto-inject anthropic-beta headers based on features used.
|
||||
|
||||
Handles:
|
||||
- context_management: adds 'context-management-2025-06-27'
|
||||
- tool_search: adds provider-specific tool search header
|
||||
|
||||
Args:
|
||||
headers: Request headers dict
|
||||
optional_params: Optional parameters including tools, context_management
|
||||
custom_llm_provider: Provider name for looking up correct tool search header
|
||||
"""
|
||||
beta_values: set = set()
|
||||
|
||||
# Get existing beta headers if any
|
||||
existing_beta = headers.get("anthropic-beta")
|
||||
beta_value = ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value
|
||||
if existing_beta is None:
|
||||
headers["anthropic-beta"] = beta_value
|
||||
elif beta_value not in [beta.strip() for beta in existing_beta.split(",")]:
|
||||
headers["anthropic-beta"] = f"{existing_beta}, {beta_value}"
|
||||
if existing_beta:
|
||||
beta_values.update(b.strip() for b in existing_beta.split(","))
|
||||
|
||||
# Check for context management
|
||||
if optional_params.get("context_management") is not None:
|
||||
beta_values.add(ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value)
|
||||
|
||||
# Check for tool search tools
|
||||
tools = optional_params.get("tools")
|
||||
if tools:
|
||||
anthropic_model_info = AnthropicModelInfo()
|
||||
if anthropic_model_info.is_tool_search_used(tools):
|
||||
# Use provider-specific tool search header
|
||||
tool_search_header = get_tool_search_beta_header(custom_llm_provider)
|
||||
beta_values.add(tool_search_header)
|
||||
|
||||
if beta_values:
|
||||
headers["anthropic-beta"] = ",".join(sorted(beta_values))
|
||||
|
||||
return headers
|
||||
|
|
|
|||
|
|
@ -664,8 +664,29 @@ class AzureChatCompletion(BaseAzureLLM, BaseLLM):
|
|||
**data, timeout=timeout
|
||||
)
|
||||
headers = dict(raw_response.headers)
|
||||
response = raw_response.parse()
|
||||
|
||||
# Convert json.JSONDecodeError to AzureOpenAIError for two critical reasons:
|
||||
#
|
||||
# 1. ROUTER BEHAVIOR: The router relies on exception.status_code to determine cooldown logic:
|
||||
# - JSONDecodeError has no status_code → router skips cooldown evaluation
|
||||
# - AzureOpenAIError has status_code → router properly evaluates for cooldown
|
||||
#
|
||||
# 2. CONNECTION CLEANUP: When response.parse() throws JSONDecodeError, the response
|
||||
# body may not be fully consumed, preventing httpx from properly returning the
|
||||
# connection to the pool. By catching the exception and accessing raw_response.status_code,
|
||||
# we trigger httpx's internal cleanup logic. Without this:
|
||||
# - parse() fails → JSONDecodeError bubbles up → httpx never knows response was acknowledged → connection leak
|
||||
# This completely eliminates "Unclosed connection" warnings during high load.
|
||||
try:
|
||||
response = raw_response.parse()
|
||||
except json.JSONDecodeError as json_error:
|
||||
raise AzureOpenAIError(
|
||||
status_code=raw_response.status_code or 500,
|
||||
message=f"Failed to parse raw Azure embedding response: {str(json_error)}"
|
||||
) from json_error
|
||||
|
||||
stringified_response = response.model_dump()
|
||||
|
||||
## LOGGING
|
||||
logging_obj.post_call(
|
||||
input=input,
|
||||
|
|
|
|||
|
|
@ -62,10 +62,10 @@ class AzureAnthropicMessagesConfig(AnthropicMessagesConfig):
|
|||
if "content-type" not in headers:
|
||||
headers["content-type"] = "application/json"
|
||||
|
||||
# Update headers with optional anthropic beta features
|
||||
headers = self._update_headers_with_optional_anthropic_beta(
|
||||
# Update headers with anthropic beta features (context management, tool search, etc.)
|
||||
headers = self._update_headers_with_anthropic_beta(
|
||||
headers=headers,
|
||||
context_management=optional_params.get("context_management"),
|
||||
optional_params=optional_params,
|
||||
)
|
||||
|
||||
return headers, api_base
|
||||
|
|
|
|||
|
|
@ -87,7 +87,7 @@ class AzureFoundryFlux2ImageEditConfig(OpenAIImageEditConfig):
|
|||
def transform_image_edit_request(
|
||||
self,
|
||||
model: str,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
|
|
@ -99,6 +99,9 @@ class AzureFoundryFlux2ImageEditConfig(OpenAIImageEditConfig):
|
|||
FLUX 2 uses the same endpoint for generation and editing,
|
||||
with the image passed as base64 in the JSON body.
|
||||
"""
|
||||
if prompt is None:
|
||||
raise ValueError("FLUX 2 image edit requires a prompt.")
|
||||
|
||||
image_b64 = self._convert_image_to_base64(image)
|
||||
|
||||
# Build request body with required params
|
||||
|
|
|
|||
|
|
@ -92,7 +92,7 @@ class BaseImageEditConfig(ABC):
|
|||
def transform_image_edit_request(
|
||||
self,
|
||||
model: str,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
|
|
|
|||
|
|
@ -425,6 +425,15 @@ def strip_bedrock_routing_prefix(model: str) -> str:
|
|||
return model
|
||||
|
||||
|
||||
def strip_bedrock_throughput_suffix(model: str) -> str:
|
||||
""" Strip throughput tier suffixes from Bedrock model names. """
|
||||
import re
|
||||
|
||||
# Pattern matches model:version:throughput where throughput is like 51k, 18k, etc.
|
||||
# Keep the model:version part, strip the :throughput suffix
|
||||
return re.sub(r"(:\d+):\d+k$", r"\1", model)
|
||||
|
||||
|
||||
def get_bedrock_base_model(model: str) -> str:
|
||||
"""
|
||||
Get the base model from the given model name.
|
||||
|
|
@ -432,9 +441,11 @@ def get_bedrock_base_model(model: str) -> str:
|
|||
Handle model names like:
|
||||
- "us.meta.llama3-2-11b-instruct-v1:0" -> "meta.llama3-2-11b-instruct-v1"
|
||||
- "bedrock/converse/model" -> "model"
|
||||
- "anthropic.claude-3-5-sonnet-20241022-v2:0:51k" -> "anthropic.claude-3-5-sonnet-20241022-v2:0"
|
||||
"""
|
||||
model = strip_bedrock_routing_prefix(model)
|
||||
model = extract_model_name_from_bedrock_arn(model)
|
||||
model = strip_bedrock_throughput_suffix(model)
|
||||
|
||||
potential_region = model.split(".", 1)[0]
|
||||
alt_potential_region = model.split("/", 1)[0]
|
||||
|
|
|
|||
|
|
@ -261,7 +261,7 @@ class BedrockImageEdit(BaseAWSLLM):
|
|||
"""
|
||||
config_class = self.get_config_class(model=model)
|
||||
config_instance = config_class()
|
||||
request_body = config_instance.transform_image_edit_request(
|
||||
request_body, _ = config_instance.transform_image_edit_request(
|
||||
model=model,
|
||||
prompt=prompt,
|
||||
image=image[0] if image else None,
|
||||
|
|
|
|||
|
|
@ -21,18 +21,18 @@ Supported models:
|
|||
API Reference: https://docs.aws.amazon.com/bedrock/latest/userguide/model-parameters.html
|
||||
"""
|
||||
|
||||
import json
|
||||
import base64
|
||||
import json
|
||||
from typing import TYPE_CHECKING, Any, Dict, Optional, Tuple
|
||||
|
||||
import httpx
|
||||
|
||||
from litellm.llms.base_llm.image_edit.transformation import BaseImageEditConfig
|
||||
from litellm.types.images.main import ImageEditOptionalRequestParams
|
||||
from litellm.types.router import GenericLiteLLMParams
|
||||
from litellm.types.llms.stability import (
|
||||
OPENAI_SIZE_TO_STABILITY_ASPECT_RATIO,
|
||||
)
|
||||
from litellm.types.router import GenericLiteLLMParams
|
||||
from litellm.types.utils import FileTypes, ImageObject, ImageResponse
|
||||
from litellm.utils import get_model_info
|
||||
|
||||
|
|
@ -153,7 +153,7 @@ class BedrockStabilityImageEditConfig(BaseImageEditConfig):
|
|||
def transform_image_edit_request(
|
||||
self,
|
||||
model: str,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
|
|
@ -164,6 +164,9 @@ class BedrockStabilityImageEditConfig(BaseImageEditConfig):
|
|||
|
||||
Returns the request body dict that will be JSON-encoded by the handler.
|
||||
"""
|
||||
if prompt is None:
|
||||
raise ValueError("Bedrock Stability image edit requires a prompt.")
|
||||
|
||||
# Build Bedrock Stability request
|
||||
data: Dict[str, Any] = {
|
||||
"prompt": prompt,
|
||||
|
|
|
|||
|
|
@ -129,6 +129,37 @@ class AmazonAnthropicClaudeMessagesConfig(
|
|||
if isinstance(cache_control, dict) and "ttl" in cache_control:
|
||||
cache_control.pop("ttl", None)
|
||||
|
||||
def _get_tool_search_beta_header_for_bedrock(
|
||||
self,
|
||||
model: str,
|
||||
tool_search_used: bool,
|
||||
programmatic_tool_calling_used: bool,
|
||||
input_examples_used: bool,
|
||||
beta_set: set,
|
||||
) -> None:
|
||||
"""
|
||||
Adjust tool search beta header for Bedrock.
|
||||
|
||||
Bedrock requires a different beta header for tool search on Opus 4 models
|
||||
when tool search is used without programmatic tool calling or input examples.
|
||||
|
||||
Note: On Amazon Bedrock, server-side tool search is only supported on Claude Opus 4
|
||||
with the `tool-search-tool-2025-10-19` beta header.
|
||||
|
||||
Ref: https://platform.claude.com/docs/en/agents-and-tools/tool-use/tool-search-tool
|
||||
|
||||
Args:
|
||||
model: The model name
|
||||
tool_search_used: Whether tool search is used
|
||||
programmatic_tool_calling_used: Whether programmatic tool calling is used
|
||||
input_examples_used: Whether input examples are used
|
||||
beta_set: The set of beta headers to modify in-place
|
||||
"""
|
||||
if tool_search_used and not (programmatic_tool_calling_used or input_examples_used):
|
||||
beta_set.discard(ANTHROPIC_TOOL_SEARCH_BETA_HEADER)
|
||||
if "opus-4" in model.lower() or "opus_4" in model.lower():
|
||||
beta_set.add("tool-search-tool-2025-10-19")
|
||||
|
||||
def transform_anthropic_messages_request(
|
||||
self,
|
||||
model: str,
|
||||
|
|
@ -189,13 +220,13 @@ class AmazonAnthropicClaudeMessagesConfig(
|
|||
)
|
||||
beta_set.update(auto_betas)
|
||||
|
||||
if (
|
||||
tool_search_used
|
||||
and not (programmatic_tool_calling_used or input_examples_used)
|
||||
):
|
||||
beta_set.discard(ANTHROPIC_TOOL_SEARCH_BETA_HEADER)
|
||||
if "opus-4" in model.lower() or "opus_4" in model.lower():
|
||||
beta_set.add("tool-search-tool-2025-10-19")
|
||||
self._get_tool_search_beta_header_for_bedrock(
|
||||
model=model,
|
||||
tool_search_used=tool_search_used,
|
||||
programmatic_tool_calling_used=programmatic_tool_calling_used,
|
||||
input_examples_used=input_examples_used,
|
||||
beta_set=beta_set,
|
||||
)
|
||||
|
||||
if beta_set:
|
||||
anthropic_messages_request["anthropic_beta"] = list(beta_set)
|
||||
|
|
|
|||
|
|
@ -245,7 +245,6 @@ class LiteLLMAiohttpTransport(AiohttpTransport):
|
|||
allow_redirects=False,
|
||||
auto_decompress=False,
|
||||
timeout=ClientTimeout(
|
||||
total=timeout.get("read"),
|
||||
sock_connect=timeout.get("connect"),
|
||||
sock_read=timeout.get("read"),
|
||||
connect=timeout.get("pool"),
|
||||
|
|
|
|||
|
|
@ -1929,6 +1929,7 @@ class BaseLLMHTTPHandler:
|
|||
# used for logging + cost tracking
|
||||
logging_obj.model_call_details["httpx_response"] = response
|
||||
|
||||
initial_response: Union[AsyncIterator, AnthropicMessagesResponse]
|
||||
if stream:
|
||||
completion_stream = anthropic_messages_provider_config.get_async_streaming_response_iterator(
|
||||
model=model,
|
||||
|
|
@ -1936,14 +1937,29 @@ class BaseLLMHTTPHandler:
|
|||
request_body=request_body,
|
||||
litellm_logging_obj=logging_obj,
|
||||
)
|
||||
return completion_stream
|
||||
initial_response = completion_stream
|
||||
else:
|
||||
return anthropic_messages_provider_config.transform_anthropic_messages_response(
|
||||
initial_response = anthropic_messages_provider_config.transform_anthropic_messages_response(
|
||||
model=model,
|
||||
raw_response=response,
|
||||
logging_obj=logging_obj,
|
||||
)
|
||||
|
||||
# Call agentic completion hooks
|
||||
final_response = await self._call_agentic_completion_hooks(
|
||||
response=initial_response,
|
||||
model=model,
|
||||
messages=messages,
|
||||
anthropic_messages_provider_config=anthropic_messages_provider_config,
|
||||
anthropic_messages_optional_request_params=anthropic_messages_optional_request_params,
|
||||
logging_obj=logging_obj,
|
||||
stream=stream or False,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
kwargs=kwargs,
|
||||
)
|
||||
|
||||
return final_response if final_response is not None else initial_response
|
||||
|
||||
def anthropic_messages_handler(
|
||||
self,
|
||||
model: str,
|
||||
|
|
@ -4334,6 +4350,111 @@ class BaseLLMHTTPHandler:
|
|||
return stream, data
|
||||
return stream, data
|
||||
|
||||
async def _call_agentic_completion_hooks(
|
||||
self,
|
||||
response: Any,
|
||||
model: str,
|
||||
messages: List[Dict],
|
||||
anthropic_messages_provider_config: "BaseAnthropicMessagesConfig",
|
||||
anthropic_messages_optional_request_params: Dict,
|
||||
logging_obj: "LiteLLMLoggingObj",
|
||||
stream: bool,
|
||||
custom_llm_provider: str,
|
||||
kwargs: Dict,
|
||||
) -> Optional[Any]:
|
||||
"""
|
||||
Call agentic completion hooks for all custom loggers.
|
||||
|
||||
1. Call async_should_run_agentic_completion to check if agentic loop is needed
|
||||
2. If yes, call async_run_agentic_completion to execute the loop
|
||||
|
||||
Returns the response from agentic loop, or None if no hook runs.
|
||||
"""
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.integrations.custom_logger import CustomLogger
|
||||
|
||||
callbacks = litellm.callbacks + (
|
||||
logging_obj.dynamic_success_callbacks or []
|
||||
)
|
||||
tools = anthropic_messages_optional_request_params.get("tools", [])
|
||||
|
||||
for callback in callbacks:
|
||||
try:
|
||||
if isinstance(callback, CustomLogger):
|
||||
# First: Check if agentic loop should run
|
||||
should_run, tool_calls = (
|
||||
await callback.async_should_run_agentic_loop(
|
||||
response=response,
|
||||
model=model,
|
||||
messages=messages,
|
||||
tools=tools,
|
||||
stream=stream,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
kwargs=kwargs,
|
||||
)
|
||||
)
|
||||
|
||||
if should_run:
|
||||
# Second: Execute agentic loop
|
||||
# Add custom_llm_provider to kwargs so the agentic loop can reconstruct the full model name
|
||||
kwargs_with_provider = kwargs.copy() if kwargs else {}
|
||||
kwargs_with_provider["custom_llm_provider"] = custom_llm_provider
|
||||
agentic_response = await callback.async_run_agentic_loop(
|
||||
tools=tool_calls,
|
||||
model=model,
|
||||
messages=messages,
|
||||
response=response,
|
||||
anthropic_messages_provider_config=anthropic_messages_provider_config,
|
||||
anthropic_messages_optional_request_params=anthropic_messages_optional_request_params,
|
||||
logging_obj=logging_obj,
|
||||
stream=stream,
|
||||
kwargs=kwargs_with_provider,
|
||||
)
|
||||
# First hook that runs agentic loop wins
|
||||
return agentic_response
|
||||
|
||||
except Exception as e:
|
||||
verbose_logger.exception(
|
||||
f"LiteLLM.AgenticHookError: Exception in agentic completion hooks: {str(e)}"
|
||||
)
|
||||
|
||||
# Check if we need to convert response to fake stream
|
||||
# This happens when:
|
||||
# 1. Stream was originally True but converted to False for WebSearch interception
|
||||
# 2. No agentic loop ran (LLM didn't use the tool)
|
||||
# 3. We have a non-streaming response that needs to be converted to streaming
|
||||
websearch_converted_stream = (
|
||||
logging_obj.model_call_details.get("websearch_interception_converted_stream", False)
|
||||
if logging_obj is not None
|
||||
else False
|
||||
)
|
||||
|
||||
if websearch_converted_stream:
|
||||
from typing import cast
|
||||
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.llms.anthropic.experimental_pass_through.messages.fake_stream_iterator import (
|
||||
FakeAnthropicMessagesStreamIterator,
|
||||
)
|
||||
from litellm.types.llms.anthropic_messages.anthropic_response import (
|
||||
AnthropicMessagesResponse,
|
||||
)
|
||||
|
||||
verbose_logger.debug(
|
||||
"WebSearchInterception: No tool call made, converting non-streaming response to fake stream"
|
||||
)
|
||||
|
||||
# Convert the non-streaming response to a fake stream
|
||||
# The response should be an AnthropicMessagesResponse (dict)
|
||||
if isinstance(response, dict):
|
||||
# Create a fake streaming iterator
|
||||
fake_stream = FakeAnthropicMessagesStreamIterator(
|
||||
response=cast(AnthropicMessagesResponse, response)
|
||||
)
|
||||
return fake_stream
|
||||
|
||||
return None
|
||||
|
||||
def _handle_error(
|
||||
self,
|
||||
e: Exception,
|
||||
|
|
@ -4453,7 +4574,7 @@ class BaseLLMHTTPHandler:
|
|||
self,
|
||||
model: str,
|
||||
image: Any,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
image_edit_provider_config: BaseImageEditConfig,
|
||||
image_edit_optional_request_params: Dict,
|
||||
custom_llm_provider: str,
|
||||
|
|
@ -4572,7 +4693,7 @@ class BaseLLMHTTPHandler:
|
|||
self,
|
||||
model: str,
|
||||
image: FileTypes,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
image_edit_provider_config: BaseImageEditConfig,
|
||||
image_edit_optional_request_params: Dict,
|
||||
custom_llm_provider: str,
|
||||
|
|
|
|||
|
|
@ -201,7 +201,7 @@ class CustomLLM(BaseLLM):
|
|||
self,
|
||||
model: str,
|
||||
image: Any,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
model_response: ImageResponse,
|
||||
api_key: Optional[str],
|
||||
api_base: Optional[str],
|
||||
|
|
@ -216,7 +216,7 @@ class CustomLLM(BaseLLM):
|
|||
self,
|
||||
model: str,
|
||||
image: Any,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
model_response: ImageResponse,
|
||||
api_key: Optional[str],
|
||||
api_base: Optional[str],
|
||||
|
|
|
|||
|
|
@ -80,7 +80,7 @@ class GeminiImageEditConfig(BaseImageEditConfig):
|
|||
def transform_image_edit_request( # type: ignore[override]
|
||||
self,
|
||||
model: str,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image_edit_optional_request_params: Dict[str, Any],
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
|
|
@ -90,6 +90,9 @@ class GeminiImageEditConfig(BaseImageEditConfig):
|
|||
if not inline_parts:
|
||||
raise ValueError("Gemini image edit requires at least one image.")
|
||||
|
||||
if prompt is None:
|
||||
raise ValueError("Gemini image edit requires a prompt.")
|
||||
|
||||
contents = [
|
||||
{
|
||||
"parts": inline_parts + [{"text": prompt}],
|
||||
|
|
|
|||
|
|
@ -1,5 +1,5 @@
|
|||
from io import BufferedReader
|
||||
from typing import TYPE_CHECKING, Any, Dict, List, Tuple, cast
|
||||
from typing import TYPE_CHECKING, Any, Dict, List, Optional, Tuple, cast
|
||||
|
||||
from httpx._types import RequestFiles
|
||||
|
||||
|
|
@ -30,7 +30,7 @@ class DallE2ImageEditConfig(OpenAIImageEditConfig):
|
|||
def transform_image_edit_request(
|
||||
self,
|
||||
model: str,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
|
|
@ -41,6 +41,9 @@ class DallE2ImageEditConfig(OpenAIImageEditConfig):
|
|||
|
||||
DALL-E-2 only accepts a single image with field name "image" (not "image[]").
|
||||
"""
|
||||
if prompt is None:
|
||||
raise ValueError("DALL-E-2 image edit requires a prompt.")
|
||||
|
||||
request = ImageEditRequestParams(
|
||||
model=model,
|
||||
image=image,
|
||||
|
|
|
|||
|
|
@ -79,7 +79,7 @@ class OpenAIImageEditConfig(BaseImageEditConfig):
|
|||
def transform_image_edit_request(
|
||||
self,
|
||||
model: str,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
|
|
@ -91,6 +91,9 @@ class OpenAIImageEditConfig(BaseImageEditConfig):
|
|||
Handles multipart/form-data for images. Uses "image[]" field name
|
||||
to support multiple images (e.g., for gpt-image-1).
|
||||
"""
|
||||
if prompt is None:
|
||||
raise ValueError("OpenAI image edit requires a prompt.")
|
||||
|
||||
request = ImageEditRequestParams(
|
||||
model=model,
|
||||
image=image,
|
||||
|
|
|
|||
|
|
@ -101,7 +101,7 @@ class RecraftImageEditConfig(BaseImageEditConfig):
|
|||
def transform_image_edit_request(
|
||||
self,
|
||||
model: str,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
|
|
@ -114,6 +114,9 @@ class RecraftImageEditConfig(BaseImageEditConfig):
|
|||
https://www.recraft.ai/docs#image-to-image
|
||||
"""
|
||||
|
||||
if prompt is None:
|
||||
raise ValueError("Recraft image edit requires a prompt.")
|
||||
|
||||
request_body: RecraftImageEditRequestParams = RecraftImageEditRequestParams(
|
||||
model=model,
|
||||
prompt=prompt,
|
||||
|
|
@ -124,7 +127,7 @@ class RecraftImageEditConfig(BaseImageEditConfig):
|
|||
#########################################################
|
||||
# Reuse OpenAI logic: Separate images as `files` and send other parameters as `data`
|
||||
#########################################################
|
||||
files_list = self._get_image_files_for_request(image=image)
|
||||
files_list = self._get_image_files_for_request(image=image) if image is not None else []
|
||||
data_without_images = {k: v for k, v in request_dict.items() if k != "image"}
|
||||
|
||||
return data_without_images, files_list
|
||||
|
|
@ -132,7 +135,7 @@ class RecraftImageEditConfig(BaseImageEditConfig):
|
|||
|
||||
def _get_image_files_for_request(
|
||||
self,
|
||||
image: FileTypes,
|
||||
image: Optional[FileTypes],
|
||||
) -> List[Tuple[str, Any]]:
|
||||
files_list: List[Tuple[str, Any]] = []
|
||||
|
||||
|
|
|
|||
|
|
@ -14,11 +14,11 @@ from httpx._types import RequestFiles
|
|||
from litellm.llms.base_llm.image_edit.transformation import BaseImageEditConfig
|
||||
from litellm.secret_managers.main import get_secret_str
|
||||
from litellm.types.images.main import ImageEditOptionalRequestParams
|
||||
from litellm.types.router import GenericLiteLLMParams
|
||||
from litellm.types.llms.stability import (
|
||||
OPENAI_SIZE_TO_STABILITY_ASPECT_RATIO,
|
||||
STABILITY_EDIT_ENDPOINTS,
|
||||
)
|
||||
from litellm.types.router import GenericLiteLLMParams
|
||||
from litellm.types.utils import FileTypes, ImageObject, ImageResponse
|
||||
from litellm.utils import get_model_info
|
||||
|
||||
|
|
@ -170,7 +170,7 @@ class StabilityImageEditConfig(BaseImageEditConfig):
|
|||
def transform_image_edit_request(
|
||||
self,
|
||||
model: str,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
|
|
@ -186,9 +186,12 @@ class StabilityImageEditConfig(BaseImageEditConfig):
|
|||
# Populate multipart form-data as separate text fields (data) and files.
|
||||
# Stability expects prompt/output_format/etc. as normal form fields, not file parts.
|
||||
data: Dict[str, Any] = {
|
||||
"prompt": prompt,
|
||||
"output_format": "png", # Default to PNG
|
||||
}
|
||||
|
||||
# Add prompt only if provided (some Stability endpoints don't require it)
|
||||
if prompt is not None:
|
||||
data["prompt"] = prompt
|
||||
# Handle image parameter - could be a single file or list
|
||||
image_file = image[0] if isinstance(image, list) else image # type: ignore
|
||||
files: Dict[str, Any] = {"image": image_file}
|
||||
|
|
|
|||
|
|
@ -665,11 +665,11 @@ def add_object_type(schema):
|
|||
if "required" in schema and schema["required"] is None:
|
||||
schema.pop("required", None)
|
||||
# Gemini doesn't accept empty properties for object types
|
||||
# If properties is empty, remove it and the type field
|
||||
# If properties is empty, remove it but keep type as object
|
||||
if not properties:
|
||||
schema.pop("properties", None)
|
||||
schema.pop("type", None)
|
||||
schema.pop("required", None)
|
||||
schema["type"] = "object"
|
||||
else:
|
||||
schema["type"] = "object"
|
||||
for name, value in properties.items():
|
||||
|
|
@ -776,6 +776,16 @@ def get_vertex_location_from_url(url: str) -> Optional[str]:
|
|||
return match.group(1) if match else None
|
||||
|
||||
|
||||
def get_vertex_model_id_from_url(url: str) -> Optional[str]:
|
||||
"""
|
||||
Get the vertex model id from the url
|
||||
|
||||
`https://${LOCATION}-aiplatform.googleapis.com/v1/projects/${PROJECT_ID}/locations/${LOCATION}/publishers/google/models/${MODEL_ID}:streamGenerateContent`
|
||||
"""
|
||||
match = re.search(r"/models/([^/:]+)", url)
|
||||
return match.group(1) if match else None
|
||||
|
||||
|
||||
def replace_project_and_location_in_route(
|
||||
requested_route: str, vertex_project: str, vertex_location: str
|
||||
) -> str:
|
||||
|
|
@ -825,6 +835,15 @@ def construct_target_url(
|
|||
if "cachedContent" in requested_route:
|
||||
vertex_version = "v1beta1"
|
||||
|
||||
# Check if the requested route starts with a version
|
||||
# e.g. /v1beta1/publishers/google/models/gemini-3-pro-preview:streamGenerateContent
|
||||
if requested_route.startswith("/v1/"):
|
||||
vertex_version = "v1"
|
||||
requested_route = requested_route.replace("/v1/", "/", 1)
|
||||
elif requested_route.startswith("/v1beta1/"):
|
||||
vertex_version = "v1beta1"
|
||||
requested_route = requested_route.replace("/v1beta1/", "/", 1)
|
||||
|
||||
base_requested_route = "{}/projects/{}/locations/{}".format(
|
||||
vertex_version, vertex_project, vertex_location
|
||||
)
|
||||
|
|
|
|||
|
|
@ -304,7 +304,7 @@ class ContextCachingEndpoints(VertexBase):
|
|||
|
||||
## CHECK IF CACHED ALREADY
|
||||
generated_cache_key = local_cache_obj.get_cache_key(
|
||||
messages=cached_messages, tools=tools
|
||||
messages=cached_messages, tools=tools, model=model
|
||||
)
|
||||
google_cache_name = self.check_cache(
|
||||
cache_key=generated_cache_key,
|
||||
|
|
@ -433,7 +433,7 @@ class ContextCachingEndpoints(VertexBase):
|
|||
|
||||
## CHECK IF CACHED ALREADY
|
||||
generated_cache_key = local_cache_obj.get_cache_key(
|
||||
messages=cached_messages, tools=tools
|
||||
messages=cached_messages, tools=tools, model=model
|
||||
)
|
||||
google_cache_name = await self.async_check_cache(
|
||||
cache_key=generated_cache_key,
|
||||
|
|
|
|||
|
|
@ -68,6 +68,8 @@ def _convert_detail_to_media_resolution_enum(
|
|||
) -> Optional[Dict[str, str]]:
|
||||
if detail == "low":
|
||||
return {"level": "MEDIA_RESOLUTION_LOW"}
|
||||
elif detail == "medium":
|
||||
return {"level": "MEDIA_RESOLUTION_MEDIUM"}
|
||||
elif detail == "high":
|
||||
return {"level": "MEDIA_RESOLUTION_HIGH"}
|
||||
return None
|
||||
|
|
|
|||
|
|
@ -151,7 +151,7 @@ class VertexAIGeminiImageEditConfig(BaseImageEditConfig, VertexLLM):
|
|||
def transform_image_edit_request( # type: ignore[override]
|
||||
self,
|
||||
model: str,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image_edit_optional_request_params: Dict[str, Any],
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
|
|
@ -161,6 +161,9 @@ class VertexAIGeminiImageEditConfig(BaseImageEditConfig, VertexLLM):
|
|||
if not inline_parts:
|
||||
raise ValueError("Vertex AI Gemini image edit requires at least one image.")
|
||||
|
||||
if prompt is None:
|
||||
raise ValueError("Vertex AI Gemini image edit requires a prompt.")
|
||||
|
||||
# Correct format for Vertex AI Gemini image editing
|
||||
contents = {
|
||||
"role": "USER",
|
||||
|
|
|
|||
|
|
@ -143,17 +143,22 @@ class VertexAIImagenImageEditConfig(BaseImageEditConfig, VertexLLM):
|
|||
def transform_image_edit_request( # type: ignore[override]
|
||||
self,
|
||||
model: str,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image_edit_optional_request_params: Dict[str, Any],
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
headers: dict,
|
||||
) -> Tuple[Dict[str, Any], Optional[RequestFiles]]:
|
||||
# Prepare reference images in the correct Imagen format
|
||||
if image is None:
|
||||
raise ValueError("Vertex AI Imagen image edit requires at least one reference image.")
|
||||
reference_images = self._prepare_reference_images(image, image_edit_optional_request_params)
|
||||
if not reference_images:
|
||||
raise ValueError("Vertex AI Imagen image edit requires at least one reference image.")
|
||||
|
||||
if prompt is None:
|
||||
raise ValueError("Vertex AI Imagen image edit requires a prompt.")
|
||||
|
||||
# Correct Imagen instances format
|
||||
instances = [
|
||||
{
|
||||
|
|
|
|||
|
|
@ -1,11 +1,16 @@
|
|||
from typing import Any, Dict, List, Optional, Tuple
|
||||
|
||||
from litellm.llms.anthropic.common_utils import AnthropicModelInfo
|
||||
from litellm.llms.anthropic.experimental_pass_through.messages.transformation import (
|
||||
AnthropicMessagesConfig,
|
||||
)
|
||||
from litellm.types.llms.anthropic import (
|
||||
ANTHROPIC_BETA_HEADER_VALUES,
|
||||
ANTHROPIC_HOSTED_TOOLS,
|
||||
)
|
||||
from litellm.types.llms.anthropic_tool_search import get_tool_search_beta_header
|
||||
from litellm.types.llms.vertex_ai import VertexPartnerProvider
|
||||
from litellm.types.router import GenericLiteLLMParams
|
||||
from litellm.types.llms.anthropic import ANTHROPIC_BETA_HEADER_VALUES, ANTHROPIC_HOSTED_TOOLS
|
||||
|
||||
from ....vertex_llm_base import VertexBase
|
||||
|
||||
|
|
@ -51,13 +56,28 @@ class VertexAIPartnerModelsAnthropicMessagesConfig(AnthropicMessagesConfig, Vert
|
|||
|
||||
headers["content-type"] = "application/json"
|
||||
|
||||
# Add web search beta header for Vertex AI only if not already set
|
||||
if "anthropic-beta" not in headers:
|
||||
tools = optional_params.get("tools", [])
|
||||
for tool in tools:
|
||||
if isinstance(tool, dict) and tool.get("type", "").startswith(ANTHROPIC_HOSTED_TOOLS.WEB_SEARCH.value):
|
||||
headers["anthropic-beta"] = ANTHROPIC_BETA_HEADER_VALUES.WEB_SEARCH_2025_03_05.value
|
||||
break
|
||||
# Add beta headers for Vertex AI
|
||||
tools = optional_params.get("tools", [])
|
||||
beta_values: set[str] = set()
|
||||
|
||||
# Get existing beta headers if any
|
||||
existing_beta = headers.get("anthropic-beta")
|
||||
if existing_beta:
|
||||
beta_values.update(b.strip() for b in existing_beta.split(","))
|
||||
|
||||
# Check for web search tool
|
||||
for tool in tools:
|
||||
if isinstance(tool, dict) and tool.get("type", "").startswith(ANTHROPIC_HOSTED_TOOLS.WEB_SEARCH.value):
|
||||
beta_values.add(ANTHROPIC_BETA_HEADER_VALUES.WEB_SEARCH_2025_03_05.value)
|
||||
break
|
||||
|
||||
# Check for tool search tools - Vertex AI uses different beta header
|
||||
anthropic_model_info = AnthropicModelInfo()
|
||||
if anthropic_model_info.is_tool_search_used(tools):
|
||||
beta_values.add(get_tool_search_beta_header("vertex_ai"))
|
||||
|
||||
if beta_values:
|
||||
headers["anthropic-beta"] = ",".join(beta_values)
|
||||
|
||||
return headers, api_base
|
||||
|
||||
|
|
|
|||
|
|
@ -69,6 +69,9 @@ class VertexAIAnthropicConfig(AnthropicConfig):
|
|||
|
||||
data.pop("model", None) # vertex anthropic doesn't accept 'model' parameter
|
||||
|
||||
# VertexAI doesn't support output_format parameter, remove it if present
|
||||
data.pop("output_format", None)
|
||||
|
||||
tools = optional_params.get("tools")
|
||||
tool_search_used = self.is_tool_search_used(tools)
|
||||
auto_betas = self.get_anthropic_beta_list(
|
||||
|
|
@ -89,6 +92,37 @@ class VertexAIAnthropicConfig(AnthropicConfig):
|
|||
|
||||
return data
|
||||
|
||||
def map_openai_params(
|
||||
self,
|
||||
non_default_params: dict,
|
||||
optional_params: dict,
|
||||
model: str,
|
||||
drop_params: bool,
|
||||
) -> dict:
|
||||
"""
|
||||
Override parent method to ensure VertexAI always uses tool-based structured outputs.
|
||||
VertexAI doesn't support the output_format parameter, so we force all models
|
||||
to use the tool-based approach for structured outputs.
|
||||
"""
|
||||
# Temporarily override model name to force tool-based approach
|
||||
# This ensures Claude Sonnet 4.5 uses tools instead of output_format
|
||||
original_model = model
|
||||
if "response_format" in non_default_params:
|
||||
model = "claude-3-sonnet-20240229" # Use a model that will use tool-based approach
|
||||
|
||||
# Call parent method with potentially modified model name
|
||||
optional_params = super().map_openai_params(
|
||||
non_default_params=non_default_params,
|
||||
optional_params=optional_params,
|
||||
model=model,
|
||||
drop_params=drop_params,
|
||||
)
|
||||
|
||||
# Restore original model name for any other processing
|
||||
model = original_model
|
||||
|
||||
return optional_params
|
||||
|
||||
def transform_response(
|
||||
self,
|
||||
model: str,
|
||||
|
|
|
|||
|
|
@ -3634,6 +3634,37 @@
|
|||
"supports_tool_choice": true,
|
||||
"supports_vision": true
|
||||
},
|
||||
"azure/gpt-5.2-codex": {
|
||||
"cache_read_input_token_cost": 1.75e-07,
|
||||
"input_cost_per_token": 1.75e-06,
|
||||
"litellm_provider": "azure",
|
||||
"max_input_tokens": 128000,
|
||||
"max_output_tokens": 16384,
|
||||
"max_tokens": 16384,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 1.4e-05,
|
||||
"supported_endpoints": [
|
||||
"/v1/chat/completions",
|
||||
"/v1/responses"
|
||||
],
|
||||
"supported_modalities": [
|
||||
"text",
|
||||
"image"
|
||||
],
|
||||
"supported_output_modalities": [
|
||||
"text"
|
||||
],
|
||||
"supports_function_calling": true,
|
||||
"supports_native_streaming": true,
|
||||
"supports_parallel_function_calling": true,
|
||||
"supports_pdf_input": true,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_reasoning": true,
|
||||
"supports_response_schema": true,
|
||||
"supports_system_messages": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_vision": true
|
||||
},
|
||||
"azure/gpt-5.2-pro": {
|
||||
"input_cost_per_token": 2.1e-05,
|
||||
"litellm_provider": "azure",
|
||||
|
|
@ -25526,13 +25557,13 @@
|
|||
"litellm_provider": "bedrock",
|
||||
"max_input_tokens": 77,
|
||||
"mode": "image_edit",
|
||||
"output_cost_per_image": 0.4
|
||||
"output_cost_per_image": 0.40
|
||||
},
|
||||
"stability.stable-creative-upscale-v1:0": {
|
||||
"litellm_provider": "bedrock",
|
||||
"max_input_tokens": 77,
|
||||
"mode": "image_edit",
|
||||
"output_cost_per_image": 0.6
|
||||
"output_cost_per_image": 0.60
|
||||
},
|
||||
"stability.stable-fast-upscale-v1:0": {
|
||||
"litellm_provider": "bedrock",
|
||||
|
|
@ -28782,13 +28813,13 @@
|
|||
"supports_web_search": true
|
||||
},
|
||||
"vertex_ai/zai-org/glm-4.7-maas": {
|
||||
"input_cost_per_token": 3e-07,
|
||||
"input_cost_per_token": 6e-07,
|
||||
"litellm_provider": "vertex_ai-zai_models",
|
||||
"max_input_tokens": 200000,
|
||||
"max_output_tokens": 128000,
|
||||
"max_tokens": 128000,
|
||||
"mode": "chat",
|
||||
"output_cost_per_token": 1.2e-06,
|
||||
"output_cost_per_token": 2.2e-06,
|
||||
"source": "https://cloud.google.com/vertex-ai/generative-ai/pricing#partner-models",
|
||||
"supports_function_calling": true,
|
||||
"supports_reasoning": true,
|
||||
|
|
@ -33930,4 +33961,4 @@
|
|||
"litellm_provider": "llamagate",
|
||||
"mode": "embedding"
|
||||
}
|
||||
}
|
||||
}
|
||||
|
|
|
|||
1
litellm/proxy/_experimental/out/404.html
Normal file
1
litellm/proxy/_experimental/out/404.html
Normal file
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue