mirror of
https://github.com/BerriAI/litellm.git
synced 2026-10-09 03:18:44 +00:00
Merge remote-tracking branch 'upstream/main' into fix-litellm-params
This commit is contained in:
 Lucky Lodhi
commit
15e8eea0b5
293 changed files with 5297 additions and 916 deletions
|
|
@ -1153,7 +1153,7 @@ jobs:
|
|||
pip install "pytest-asyncio==0.21.1"
|
||||
pip install "respx==0.22.0"
|
||||
pip install "pydantic==2.10.2"
|
||||
pip install "mcp==1.10.1"
|
||||
pip install "mcp==1.21.2"
|
||||
# Run pytest and generate JUnit XML report
|
||||
- run:
|
||||
name: Run tests
|
||||
|
|
|
|||
|
|
@ -374,7 +374,9 @@ Support for more providers. Missing a provider or LLM Platform, raise a [feature
|
|||
1. (In root) create virtual environment `python -m venv .venv`
|
||||
2. Activate virtual environment `source .venv/bin/activate`
|
||||
3. Install dependencies `pip install -e ".[all]"`
|
||||
4. Start proxy backend `python litellm/proxy_cli.py`
|
||||
4. `pip install prisma`
|
||||
5. `prisma generate`
|
||||
6. Start proxy backend `python litellm/proxy/proxy_cli.py`
|
||||
|
||||
### Frontend
|
||||
1. Navigate to `ui/litellm-dashboard`
|
||||
|
|
|
|||
|
|
@ -95,4 +95,40 @@
|
|||
"LiteLLM",
|
||||
"Quickstart"
|
||||
]
|
||||
},
|
||||
{
|
||||
"title": "AI Coding Tool Usage Tracking",
|
||||
"description": "This is a guide to tracking usage for AI coding tools monitor the use of Claude Code , Google Antigravity, OpenAI Codex, Roo Code etc. through LiteLLM.",
|
||||
"url": "https://docs.litellm.ai/docs/tutorials/cost_tracking_coding",
|
||||
"date": "2026-01-17",
|
||||
"version": "1.0.0",
|
||||
"tags": [
|
||||
"Claude Code",
|
||||
"Gemini CLI",
|
||||
"OpenAI Codex",
|
||||
"LiteLLM"
|
||||
]
|
||||
},
|
||||
{
|
||||
"title": "Use Web Search with Claude Code (across OpenAI/Anthropic/Gemini/etc.)",
|
||||
"description": "This is a guide for using Web Search with Claude Code via LiteLLM.",
|
||||
"url": "https://docs.litellm.ai/docs/tutorials/claude_code_websearch",
|
||||
"date": "2026-01-17",
|
||||
"version": "1.0.0",
|
||||
"tags": [
|
||||
"Claude Code",
|
||||
"LiteLLM",
|
||||
"Web Search"
|
||||
]
|
||||
},
|
||||
{
|
||||
"title": "Track Claude Code Usage per user via Custom Headers",
|
||||
"description": "This is a guide for tracking claude code user usage by passing a customer ID header.",
|
||||
"url": "https://docs.litellm.ai/docs/tutorials/claude_code_customer_tracking",
|
||||
"date": "2026-01-17",
|
||||
"version": "1.0.0",
|
||||
"tags": [
|
||||
"Claude Code",
|
||||
"LiteLLM"
|
||||
]
|
||||
}]
|
||||
|
|
@ -1,6 +1,8 @@
|
|||
[supervisord]
|
||||
nodaemon=true
|
||||
loglevel=info
|
||||
logfile=/tmp/supervisord.log
|
||||
pidfile=/tmp/supervisord.pid
|
||||
|
||||
[group:litellm]
|
||||
programs=main,health
|
||||
|
|
|
|||
|
|
@ -1,45 +1,100 @@
|
|||
# Contributing - UI
|
||||
|
||||
Here's how to run the LiteLLM UI locally for making changes:
|
||||
Thanks for contributing to the LiteLLM UI! This guide will help you set up your local development environment.
|
||||
|
||||
|
||||
## 1. Clone the repo
|
||||
|
||||
## 1. Clone the repo
|
||||
```bash
|
||||
git clone https://github.com/BerriAI/litellm.git
|
||||
cd litellm
|
||||
```
|
||||
|
||||
## 2. Start the UI + Proxy
|
||||
## 2. Start the Proxy
|
||||
|
||||
**2.1 Start the proxy on port 4000**
|
||||
Create a config file (e.g., `config.yaml`):
|
||||
|
||||
Tell the proxy where the UI is located
|
||||
```bash
|
||||
DATABASE_URL = "postgresql://<user>:<password>@<host>:<port>/<dbname>"
|
||||
LITELLM_MASTER_KEY = "sk-1234"
|
||||
STORE_MODEL_IN_DB = "True"
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-4o
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
|
||||
general_settings:
|
||||
master_key: sk-1234
|
||||
database_url: postgresql://<user>:<password>@<host>:<port>/<dbname>
|
||||
store_model_in_db: true
|
||||
```
|
||||
|
||||
Start the proxy on port 4000:
|
||||
|
||||
```bash
|
||||
cd litellm/litellm/proxy
|
||||
python3 proxy_cli.py --config /path/to/config.yaml --port 4000
|
||||
poetry run litellm --config config.yaml --port 4000
|
||||
```
|
||||
|
||||
**2.2 Start the UI**
|
||||
The UI comes pre-built in the repo. Access it at `http://localhost:4000/ui`
|
||||
|
||||
Set the mode as development (this will assume the proxy is running on localhost:4000)
|
||||
```bash
|
||||
npm install # install dependencies
|
||||
```
|
||||
## 3. UI Development
|
||||
|
||||
There are two options for UI development:
|
||||
|
||||
### Option A: Development Mode (Hot Reload)
|
||||
|
||||
This runs the UI on port 3000 with hot reload. The proxy runs on port 4000.
|
||||
|
||||
```bash
|
||||
cd litellm/ui/litellm-dashboard
|
||||
|
||||
cd ui/litellm-dashboard
|
||||
npm install
|
||||
npm run dev
|
||||
|
||||
# starts on http://0.0.0.0:3000
|
||||
```
|
||||
|
||||
## 3. Go to local UI
|
||||
**Login flow:**
|
||||
1. Go to `http://localhost:3000`
|
||||
2. You'll be redirected to `http://localhost:4000/ui` for login
|
||||
3. After logging in, manually navigate back to `http://localhost:3000/`
|
||||
4. You're now authenticated and can develop with hot reload
|
||||
|
||||
:::note
|
||||
If you experience redirect loops or authentication issues, clear your browser cookies for localhost or use Build Mode instead.
|
||||
:::
|
||||
|
||||
### Option B: Build Mode
|
||||
|
||||
This builds the UI and copies it to the proxy. Changes require rebuilding.
|
||||
|
||||
1. Make your code changes in `ui/litellm-dashboard/src/`
|
||||
|
||||
2. Build the UI
|
||||
```bash
|
||||
cd ui/litellm-dashboard
|
||||
npm install
|
||||
npm run build
|
||||
```
|
||||
|
||||
After building, copy the output to the proxy:
|
||||
|
||||
```bash
|
||||
http://0.0.0.0:3000
|
||||
```
|
||||
cp -r out/* ../../litellm/proxy/_experimental/out/
|
||||
```
|
||||
|
||||
Then restart the proxy and access the UI at `http://localhost:4000/ui`
|
||||
|
||||
## 4. Submitting a PR
|
||||
|
||||
1. Create a new branch for your changes:
|
||||
```bash
|
||||
git checkout -b feat/your-feature-name
|
||||
```
|
||||
|
||||
2. Stage and commit your changes:
|
||||
```bash
|
||||
git add .
|
||||
git commit -m "feat: description of your changes"
|
||||
```
|
||||
|
||||
3. Push to your fork:
|
||||
```bash
|
||||
git push origin feat/your-feature-name
|
||||
```
|
||||
|
||||
4. Create a Pull Request on GitHub following the [PR template](https://github.com/BerriAI/litellm/blob/main/.github/pull_request_template.md)
|
||||
|
|
|
|||
|
|
@ -173,6 +173,14 @@ Stability AI returns images in base64 format. The response is OpenAI-compatible:
|
|||
|
||||
Stability AI supports various image editing operations including inpainting, upscaling, outpainting, background removal, and more.
|
||||
|
||||
:::info Optional Parameters
|
||||
**Important:** Different Stability models have different parameter requirements:
|
||||
- Some models don't require a `prompt` (e.g., upscaling, background removal)
|
||||
- The `style-transfer` model uses `init_image` and `style_image` instead of `image`
|
||||
- The `outpaint` model requires numeric parameters (`left`, `right`, `up`, `down`)
|
||||
LiteLLM automatically handles these differences for you.
|
||||
:::
|
||||
|
||||
### Usage - LiteLLM Python SDK
|
||||
|
||||
#### Inpainting (Edit with Mask)
|
||||
|
|
@ -217,11 +225,11 @@ response = image_edit(
|
|||
creativity=0.3, # 0-0.35, higher = more creative
|
||||
)
|
||||
|
||||
# Fast upscaling - quick upscaling
|
||||
# Fast upscaling - quick upscaling (no prompt needed)
|
||||
response = image_edit(
|
||||
model="stability/stable-fast-upscale-v1:0",
|
||||
image=open("low_res_image.png", "rb"),
|
||||
prompt="Quickly upscale this image",
|
||||
# No prompt required for fast upscale
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
|
@ -259,7 +267,7 @@ os.environ['STABILITY_API_KEY'] = "your-api-key"
|
|||
response = image_edit(
|
||||
model="stability/stable-image-remove-background-v1:0",
|
||||
image=open("portrait.png", "rb"),
|
||||
prompt="Remove the background",
|
||||
# No prompt required for fast upscale
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
|
@ -329,10 +337,29 @@ response = image_edit(
|
|||
model="stability/stable-image-erase-object-v1:0",
|
||||
image=open("scene.png", "rb"),
|
||||
mask=open("object_mask.png", "rb"), # Mask the object to erase
|
||||
prompt="Remove the object",
|
||||
# No prompt needed
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
#### Style Transfer
|
||||
|
||||
```python showLineNumbers
|
||||
from litellm import image_edit
|
||||
import os
|
||||
|
||||
os.environ['STABILITY_API_KEY'] = "your-api-key"
|
||||
|
||||
# Transfer style from one image to another
|
||||
# Note: Uses init_image (via image param) and style_image
|
||||
response = image_edit(
|
||||
model="stability/stable-style-transfer-v1:0",
|
||||
image=open("content_image.png", "rb"), # Maps to init_image
|
||||
style_image=open("style_reference.png", "rb"), # Style to apply
|
||||
fidelity=0.5, # 0-1, balance between content and style
|
||||
# No prompt needed
|
||||
)
|
||||
|
||||
print(response)
|
||||
|
||||
### Supported Image Edit Models
|
||||
|
||||
|
|
@ -419,6 +446,23 @@ response = image_edit(
|
|||
)
|
||||
print(response)
|
||||
```
|
||||
# Fast upscale without prompt
|
||||
response = image_edit(
|
||||
model="bedrock/stability.stable-fast-upscale-v1:0",
|
||||
image=open("low_res_image.png", "rb"),
|
||||
)
|
||||
|
||||
# Outpaint with numeric parameters
|
||||
response = image_edit(
|
||||
model="bedrock/stability.stable-outpaint-v1:0",
|
||||
image=open("original_image.png", "rb"),
|
||||
left=100, # Automatically converted to int
|
||||
right=100,
|
||||
up=50,
|
||||
down=50,
|
||||
)
|
||||
|
||||
print(response)
|
||||
|
||||
### Supported Bedrock Stability Models
|
||||
|
||||
|
|
|
|||
|
|
@ -1390,6 +1390,77 @@ model_list:
|
|||
|
||||
|
||||
|
||||
### **Workload Identity Federation**
|
||||
|
||||
LiteLLM supports [Google Cloud Workload Identity Federation (WIF)](https://cloud.google.com/iam/docs/workload-identity-federation), which allows you to grant on-premises or multi-cloud workloads access to Google Cloud resources without using a service account key. This is the recommended approach for workloads running in other cloud environments (AWS, Azure, etc.) or on-premises.
|
||||
|
||||
To use Workload Identity Federation, pass the path to your WIF credentials configuration file via `vertex_credentials`:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="vertex_ai/gemini-1.5-pro",
|
||||
messages=[{"role": "user", "content": "Hello!"}],
|
||||
vertex_credentials="/path/to/wif-credentials.json", # 👈 WIF credentials file
|
||||
vertex_project="your-gcp-project-id",
|
||||
vertex_location="us-central1"
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gemini-model
|
||||
litellm_params:
|
||||
model: vertex_ai/gemini-1.5-pro
|
||||
vertex_project: your-gcp-project-id
|
||||
vertex_location: us-central1
|
||||
vertex_credentials: /path/to/wif-credentials.json # 👈 WIF credentials file
|
||||
```
|
||||
|
||||
Alternatively, you can create credentials in **LLM Credentials** in the LiteLLM UI and use those to authenticate your models:
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gemini-model
|
||||
litellm_params:
|
||||
model: vertex_ai/gemini-1.5-pro
|
||||
vertex_project: your-gcp-project-id
|
||||
vertex_location: us-central1
|
||||
litellm_credential_name: my-vertex-wif-credential # 👈 Reference credential stored in UI
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
**WIF Credentials File Format**
|
||||
|
||||
Your WIF credentials JSON file typically looks like this (for AWS federation):
|
||||
|
||||
```json
|
||||
{
|
||||
"type": "external_account",
|
||||
"audience": "//iam.googleapis.com/projects/PROJECT_NUMBER/locations/global/workloadIdentityPools/POOL_ID/providers/PROVIDER_ID",
|
||||
"subject_token_type": "urn:ietf:params:aws:token-type:aws4_request",
|
||||
"service_account_impersonation_url": "https://iamcredentials.googleapis.com/v1/projects/-/serviceAccounts/SERVICE_ACCOUNT_EMAIL:generateAccessToken",
|
||||
"token_url": "https://sts.googleapis.com/v1/token",
|
||||
"credential_source": {
|
||||
"environment_id": "aws1",
|
||||
"region_url": "http://169.254.169.254/latest/meta-data/placement/availability-zone",
|
||||
"url": "http://169.254.169.254/latest/meta-data/iam/security-credentials",
|
||||
"regional_cred_verification_url": "https://sts.{region}.amazonaws.com?Action=GetCallerIdentity&Version=2011-06-15"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
For more details on setting up Workload Identity Federation, see [Google Cloud WIF documentation](https://cloud.google.com/iam/docs/workload-identity-federation).
|
||||
|
||||
### **Environment Variables**
|
||||
|
||||
You can set:
|
||||
|
|
|
|||
106
docs/my-website/docs/proxy/deleted_keys_teams.md
Normal file
106
docs/my-website/docs/proxy/deleted_keys_teams.md
Normal file
|
|
@ -0,0 +1,106 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Deleted Keys & Teams Audit Logs
|
||||
|
||||
<Image img={require('../../img/ui_deleted_keys_table.png')} />
|
||||
|
||||
View deleted API keys and teams along with their spend and budget information at the time of deletion for auditing and compliance purposes.
|
||||
|
||||
## Overview
|
||||
|
||||
The Deleted Keys & Teams feature provides a comprehensive audit trail for deleted entities in your LiteLLM proxy. This feature was implemented to easily allow audits of which key or team was deleted along with the spend/budget at the time of deletion.
|
||||
|
||||
When a key or team is deleted, LiteLLM automatically captures:
|
||||
|
||||
- **Deletion timestamp** - When the entity was deleted
|
||||
- **Deleted by** - Who performed the deletion action
|
||||
- **Spend at deletion** - The total spend accumulated at the time of deletion
|
||||
- **Original budget** - The budget that was set for the entity before deletion
|
||||
- **Entity details** - Key or team identification information
|
||||
|
||||
This information is preserved even after deletion, allowing you to maintain accurate financial records and audit trails for compliance purposes.
|
||||
|
||||
## Viewing Deleted Keys
|
||||
|
||||
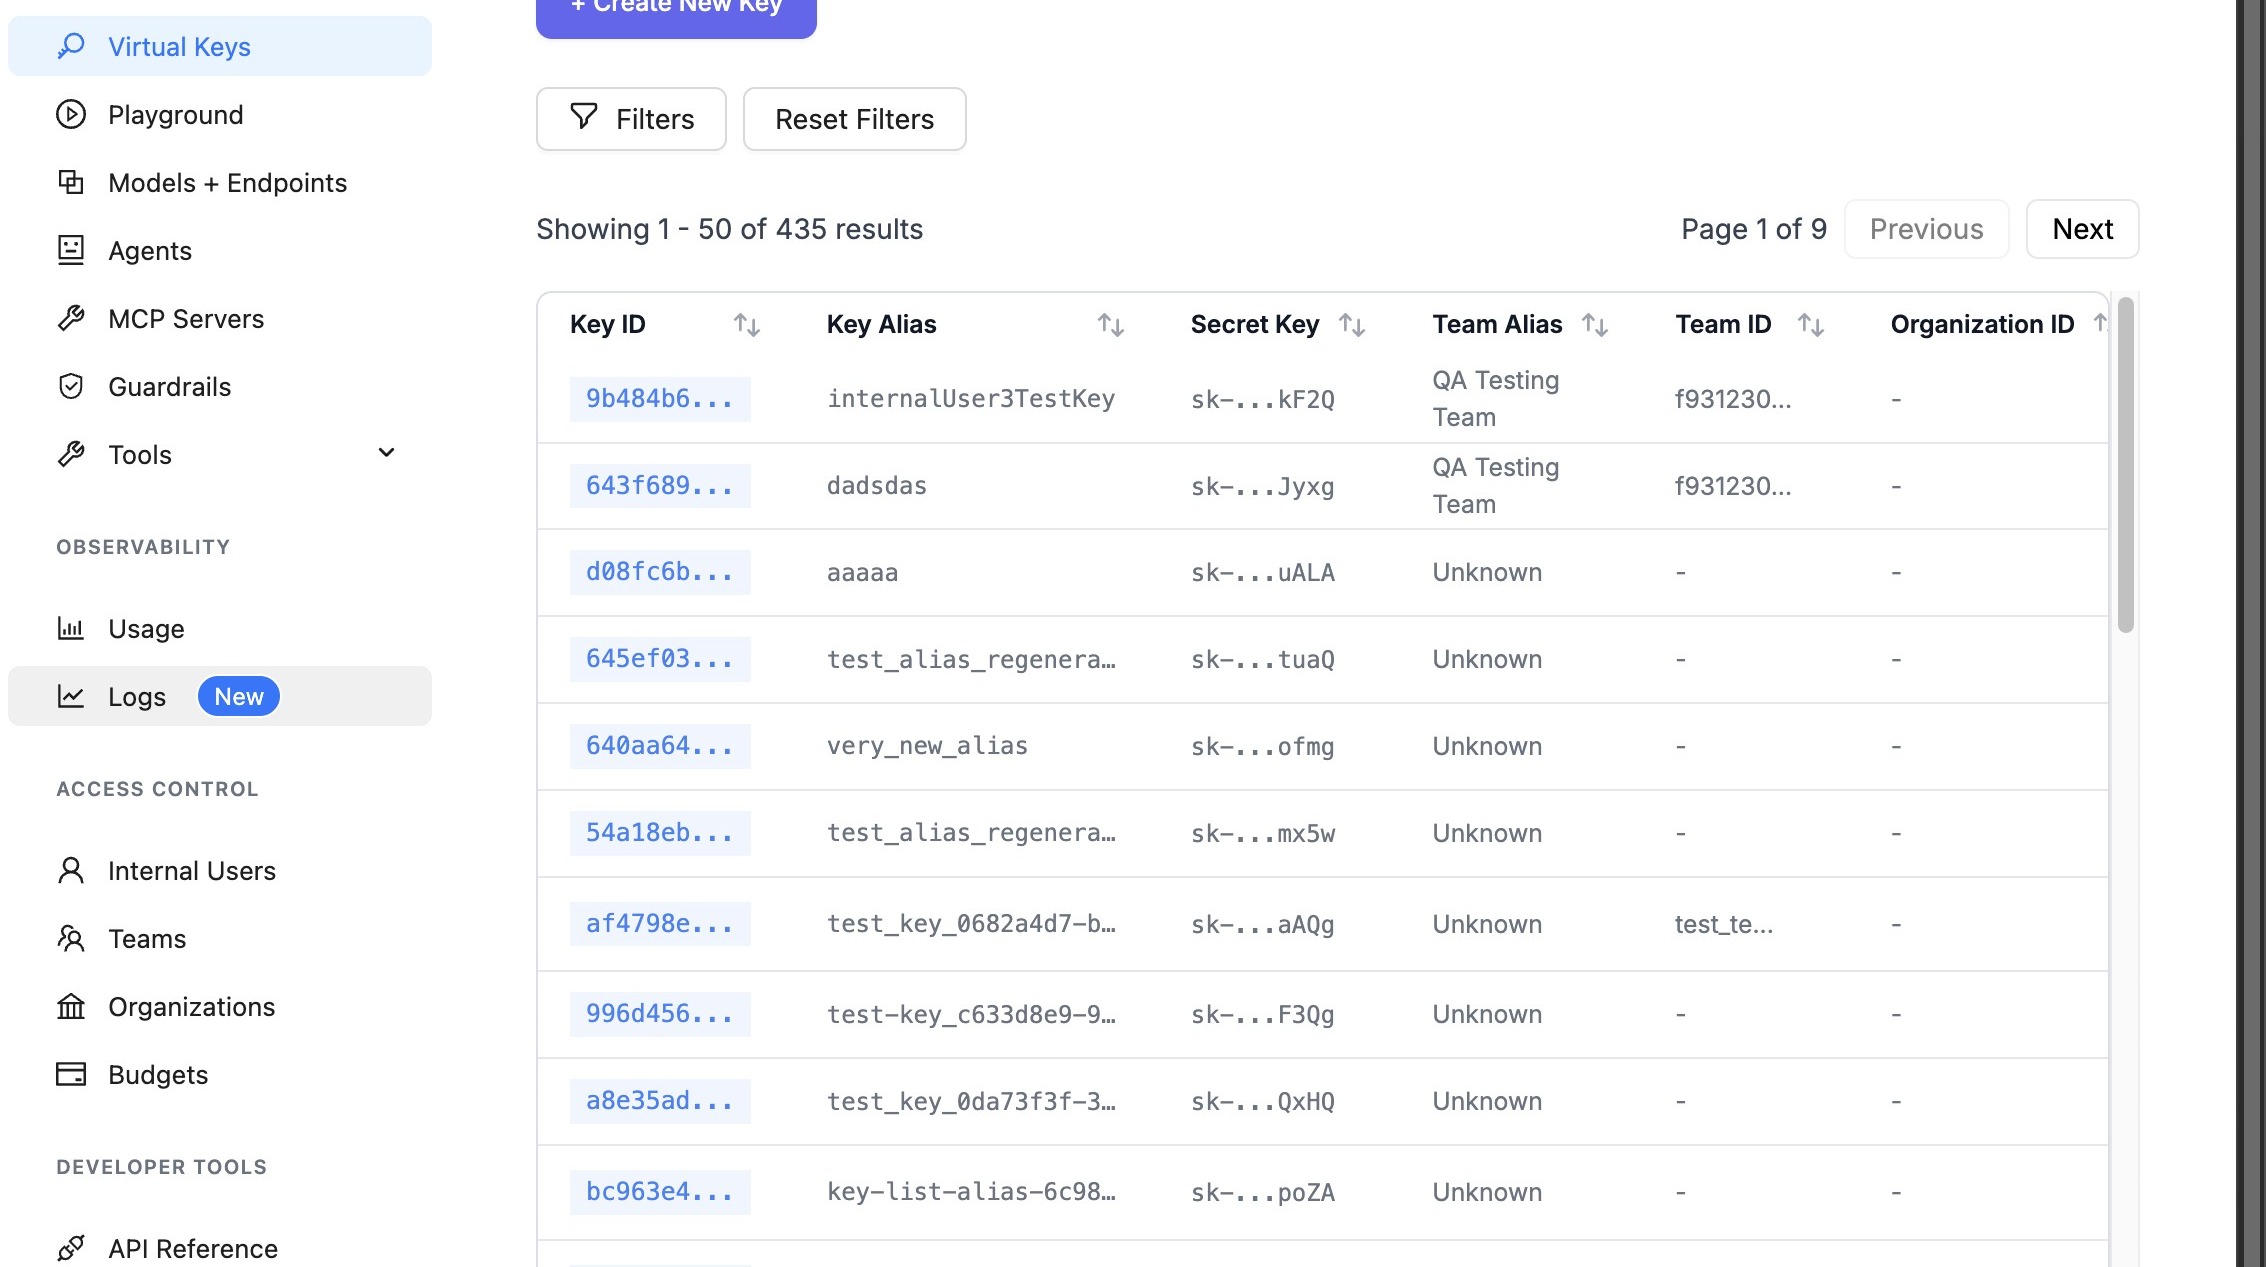
### Step 1: Navigate to API Keys Page
|
||||
|
||||
Navigate to the API Keys page in the LiteLLM UI:
|
||||
|
||||
```
|
||||
http://localhost:4000/ui/?login=success&page=api-keys
|
||||
```
|
||||
|
||||
|
||||
|
||||
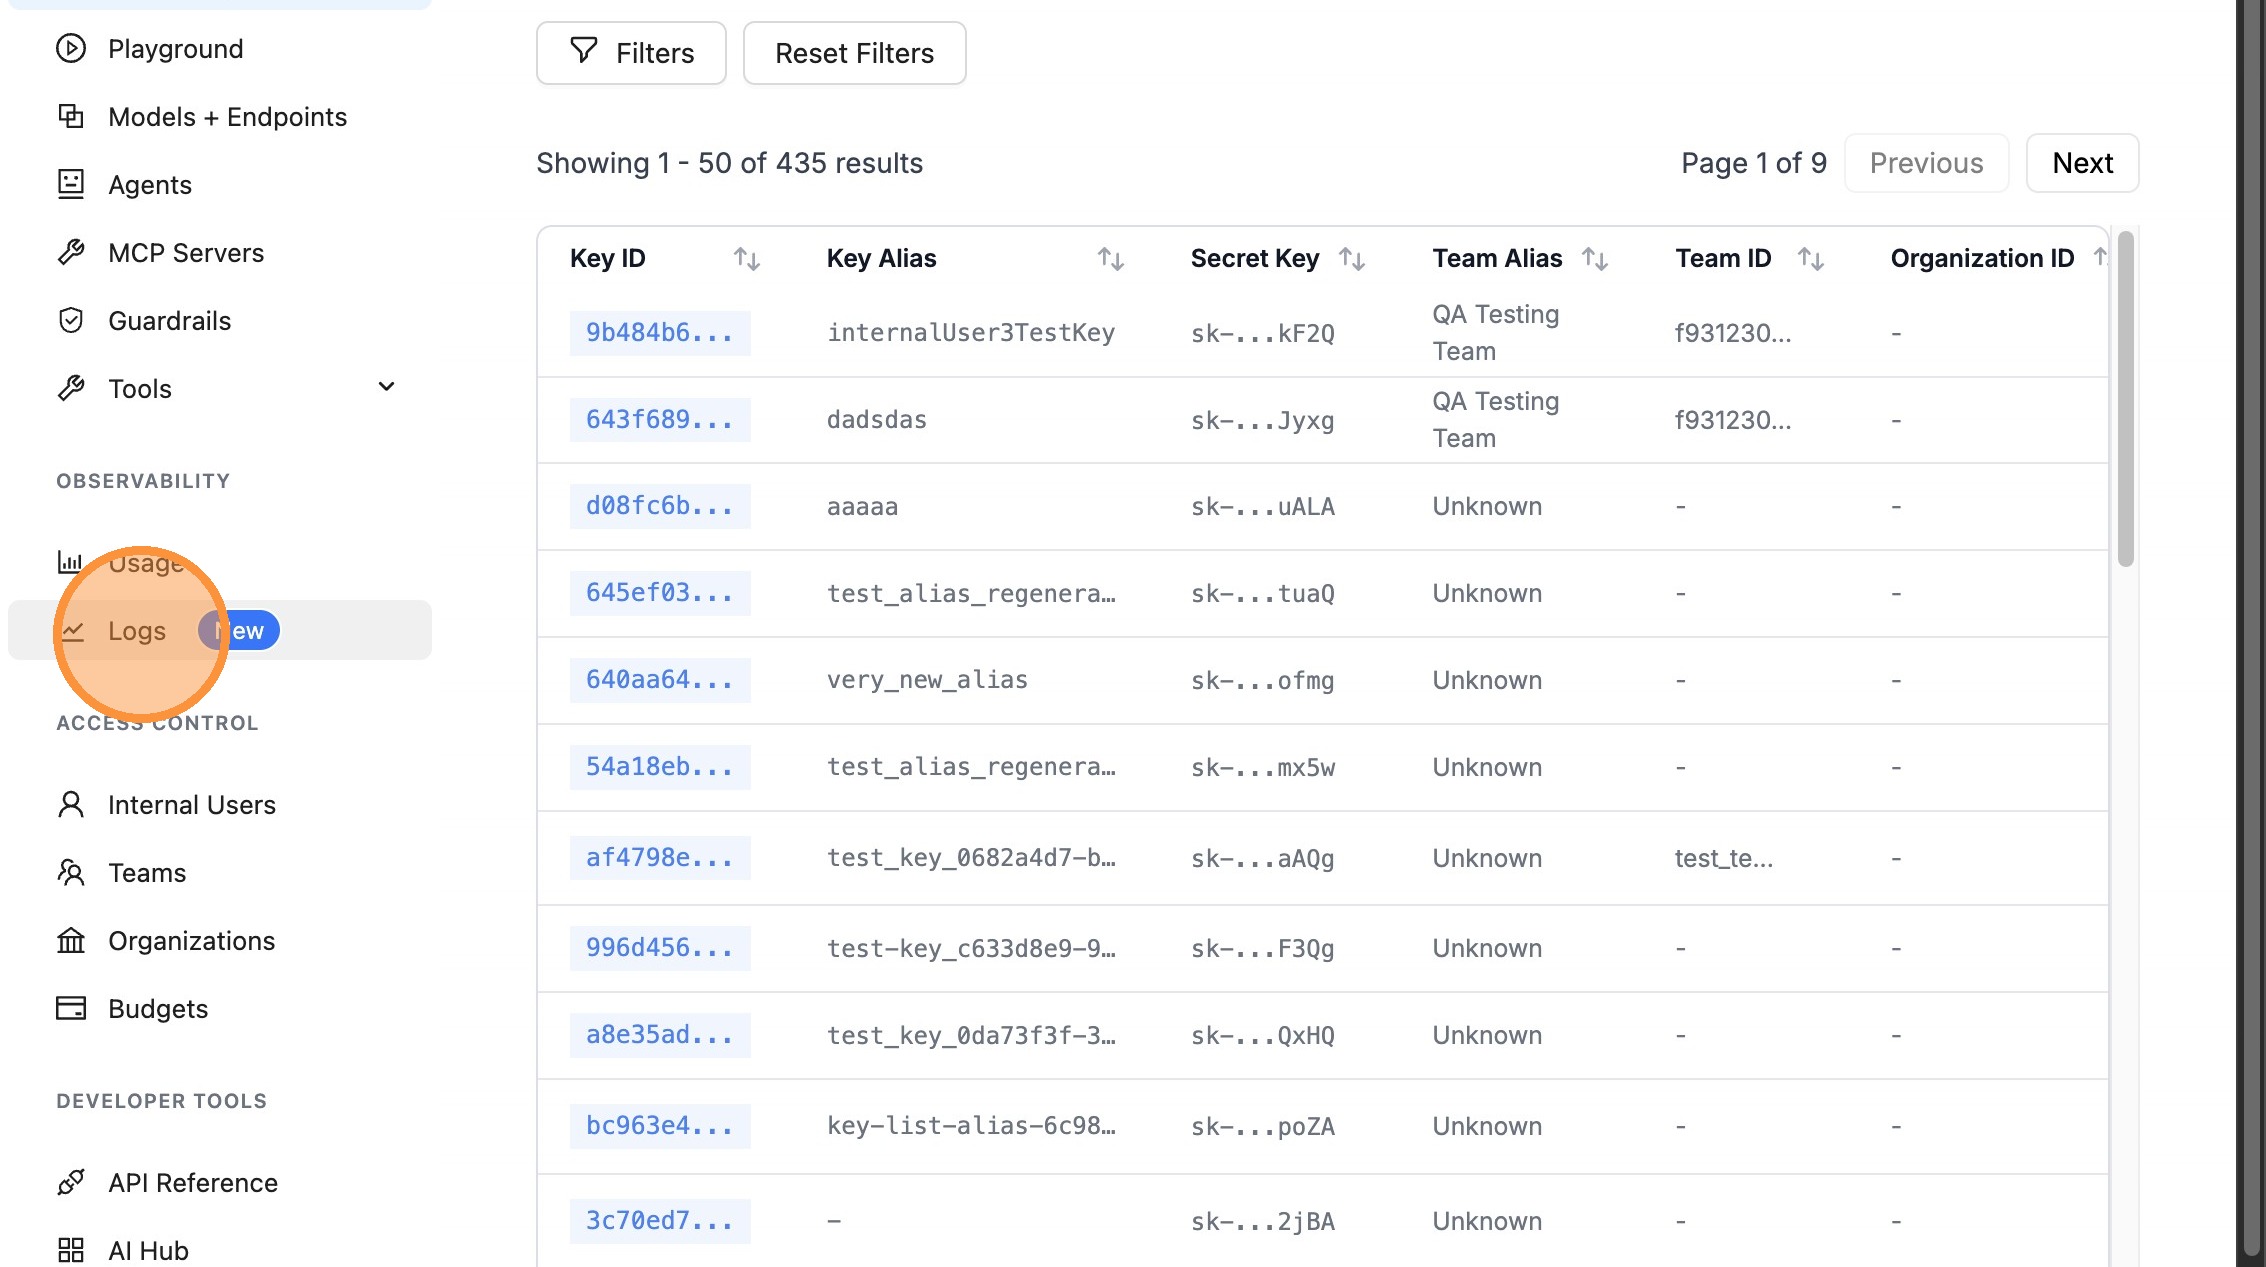
### Step 2: Access Logs Section
|
||||
|
||||
Click on the "Logs" menu item in the navigation.
|
||||
|
||||
|
||||
|
||||
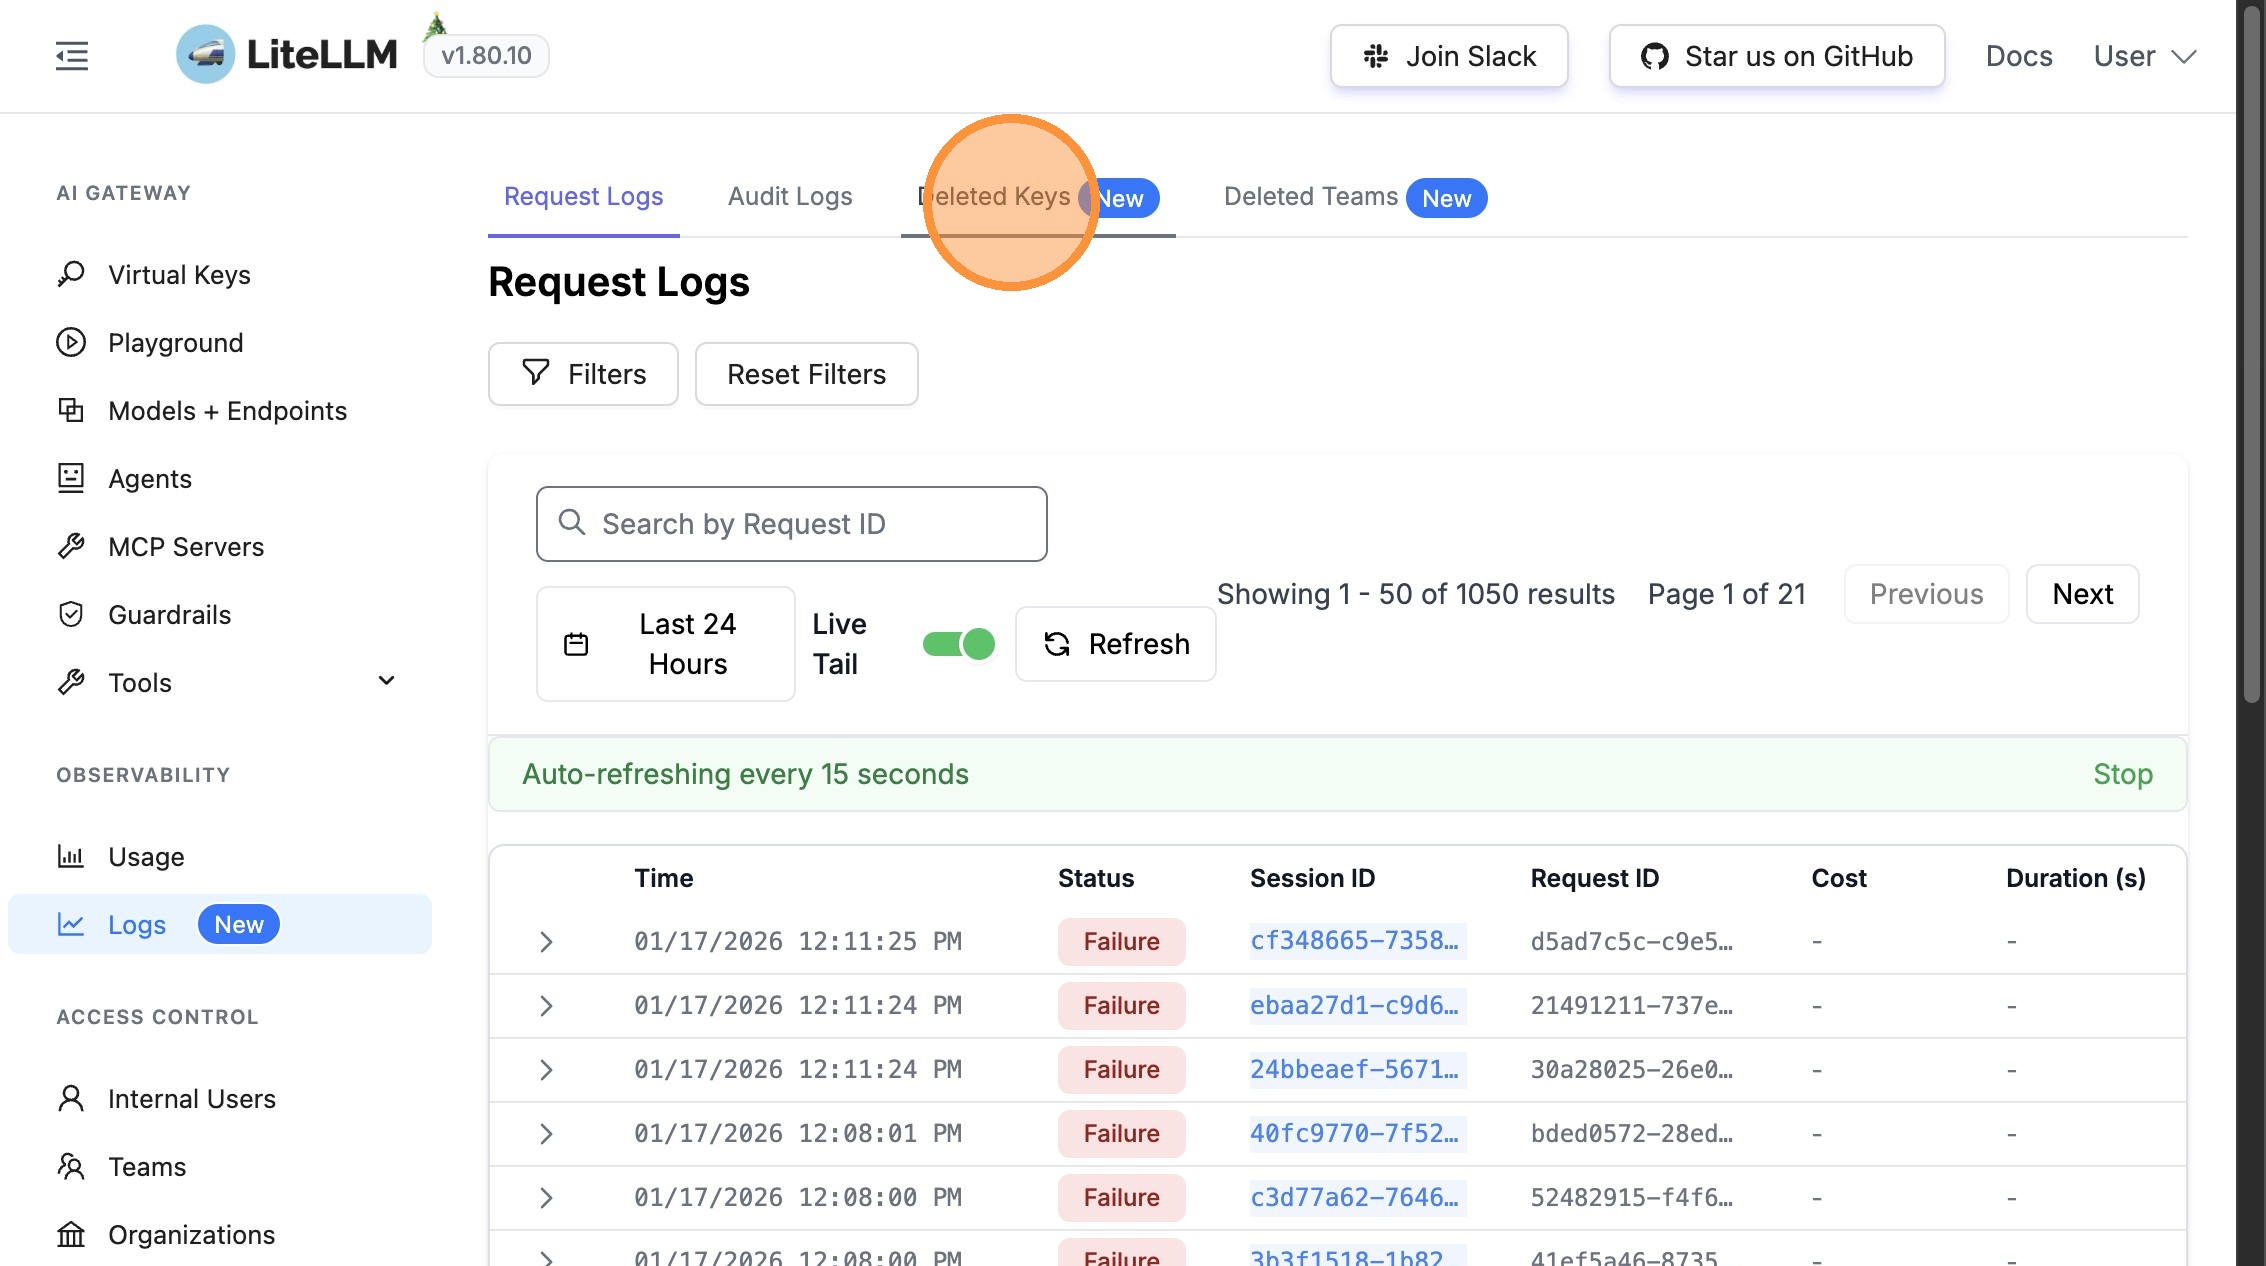
### Step 3: View Deleted Keys
|
||||
|
||||
Click on "Deleted Keys" to view the table of all deleted API keys.
|
||||
|
||||
|
||||
|
||||
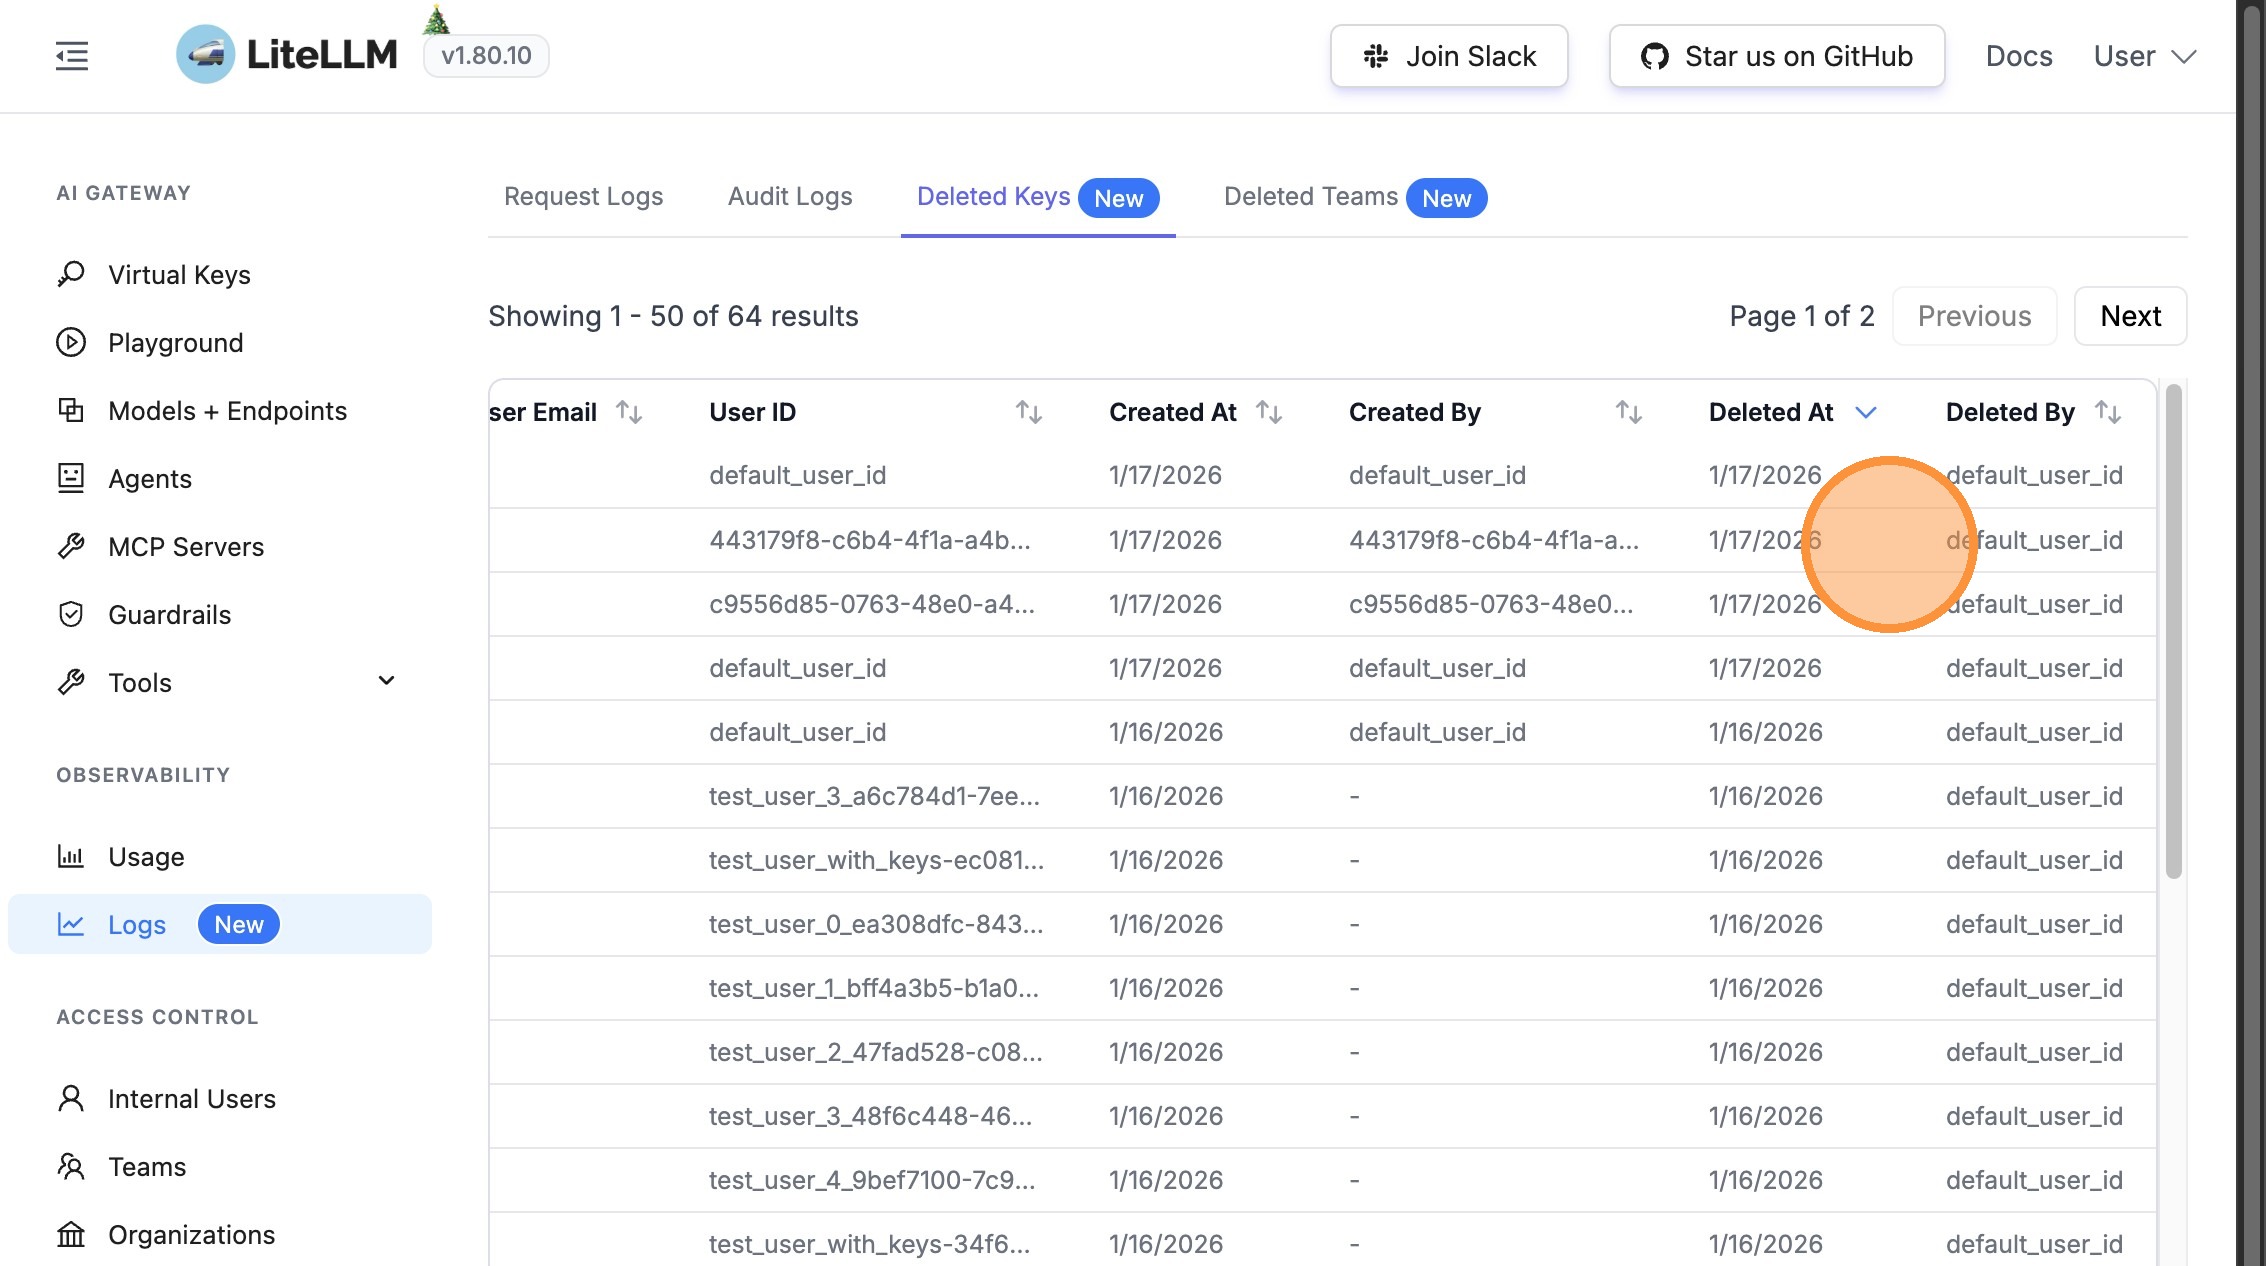
### Step 4: Review Deletion Information
|
||||
|
||||
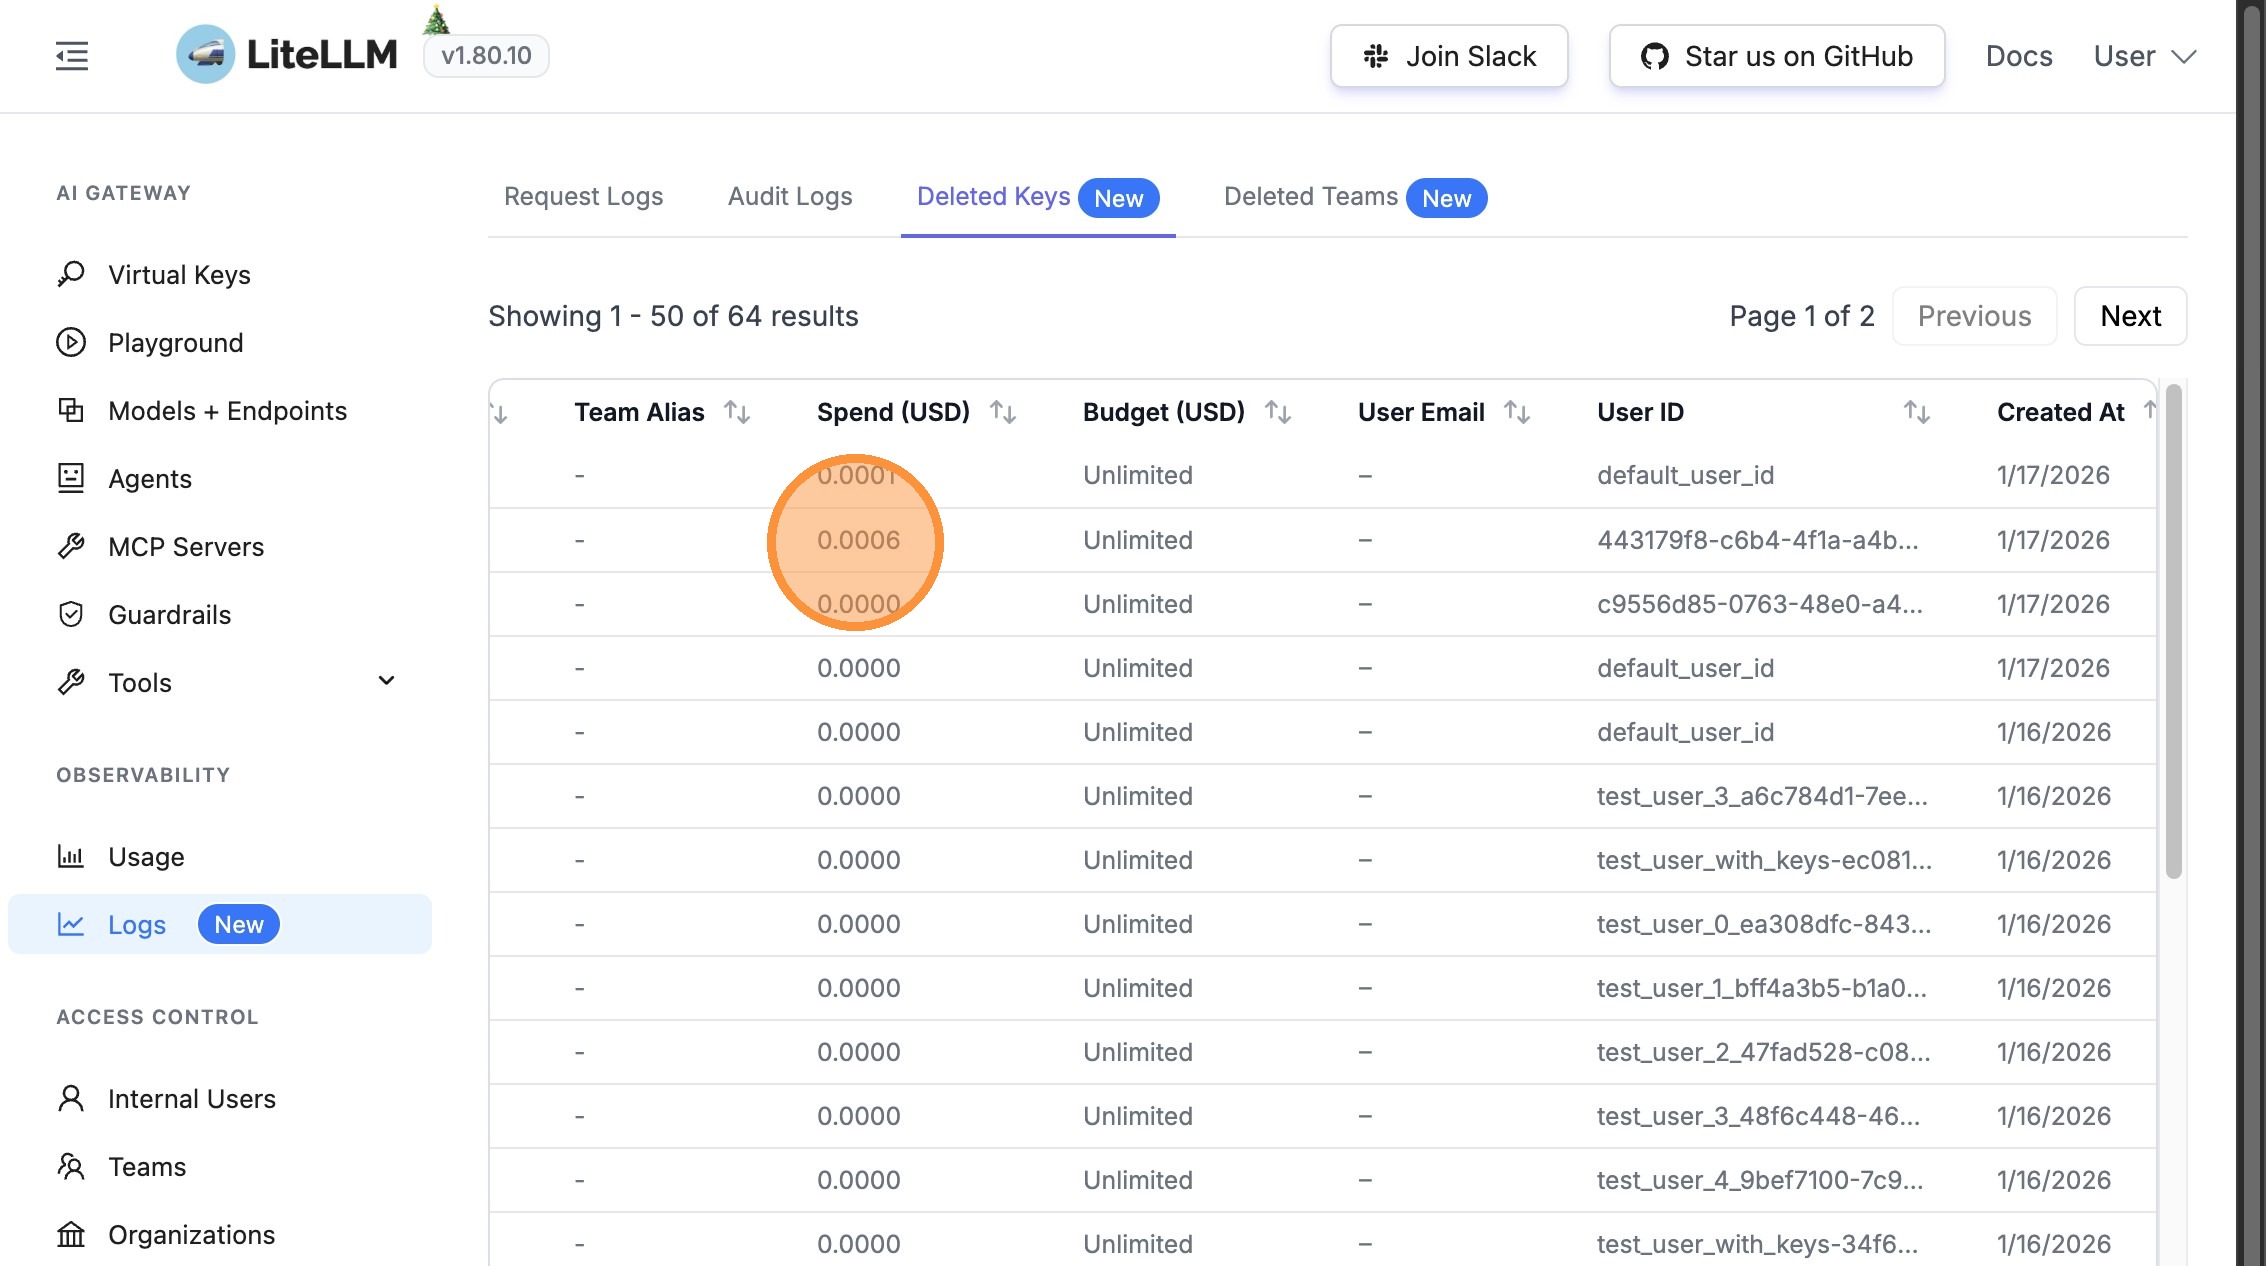
The Deleted Keys table includes comprehensive information about each deleted key:
|
||||
|
||||
- **When** the key was deleted (timestamp)
|
||||
- **Who** deleted the key (user/admin information)
|
||||
- **Key identification** details
|
||||
|
||||
|
||||
|
||||
### Step 5: View Financial Information
|
||||
|
||||
The table also displays financial information captured at the time of deletion:
|
||||
|
||||
- **Spend at deletion** - Total spend accumulated when the key was deleted
|
||||
- **Original budget** - The budget limit that was set for the key
|
||||
|
||||
|
||||
|
||||
## Viewing Deleted Teams
|
||||
|
||||
### Step 1: Access Deleted Teams
|
||||
|
||||
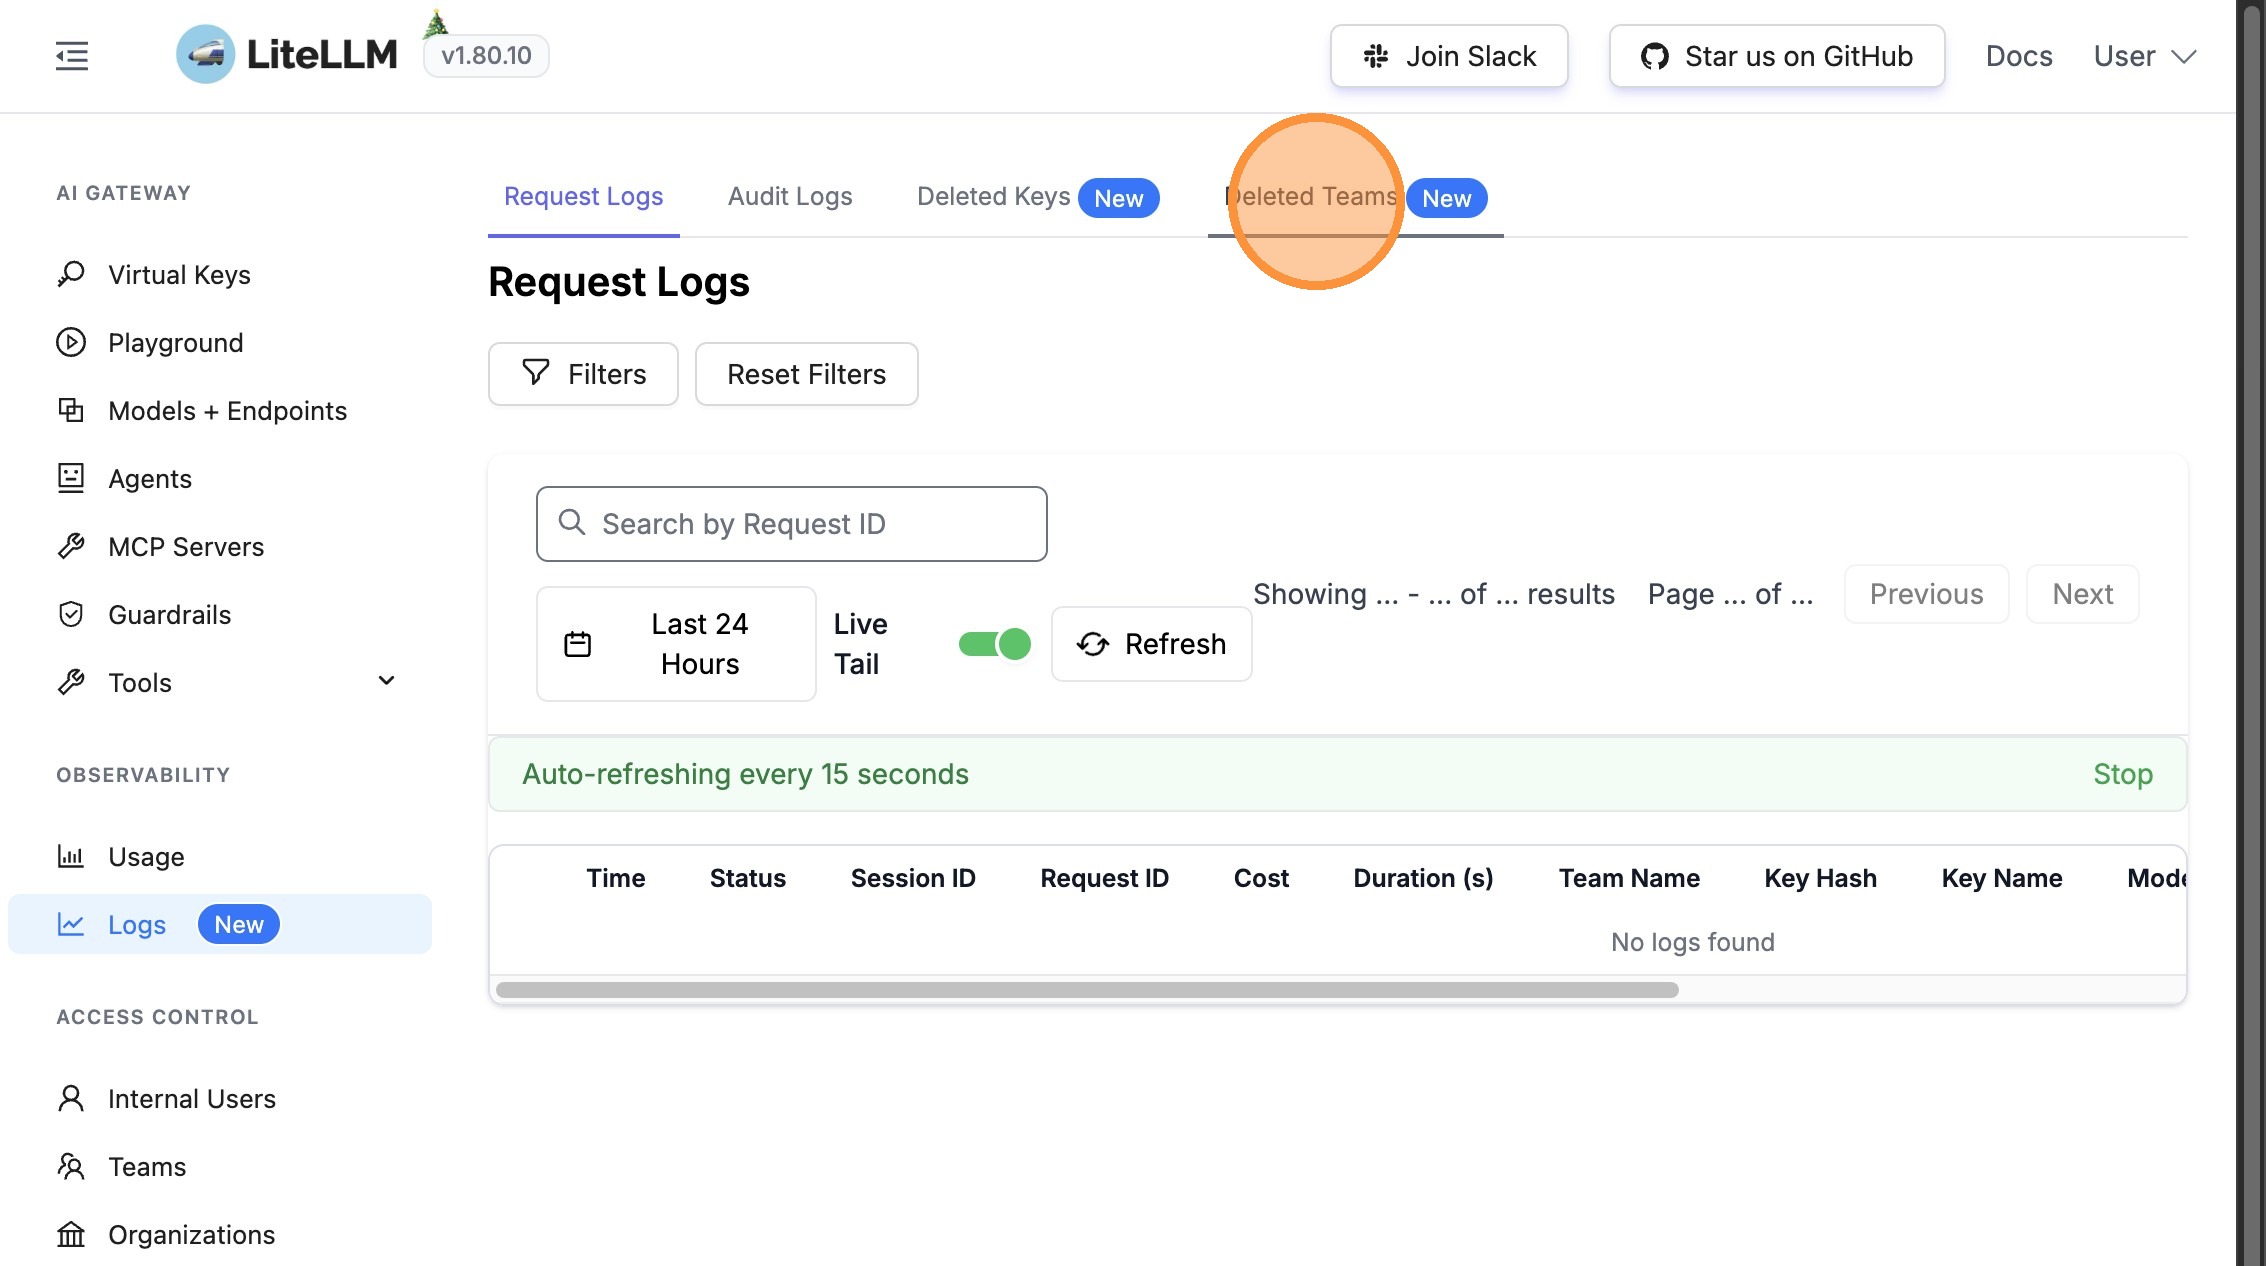
From the Logs section, click on "Deleted Teams" to view all deleted teams.
|
||||
|
||||
|
||||
|
||||
### Step 2: Review Team Deletion Information
|
||||
|
||||
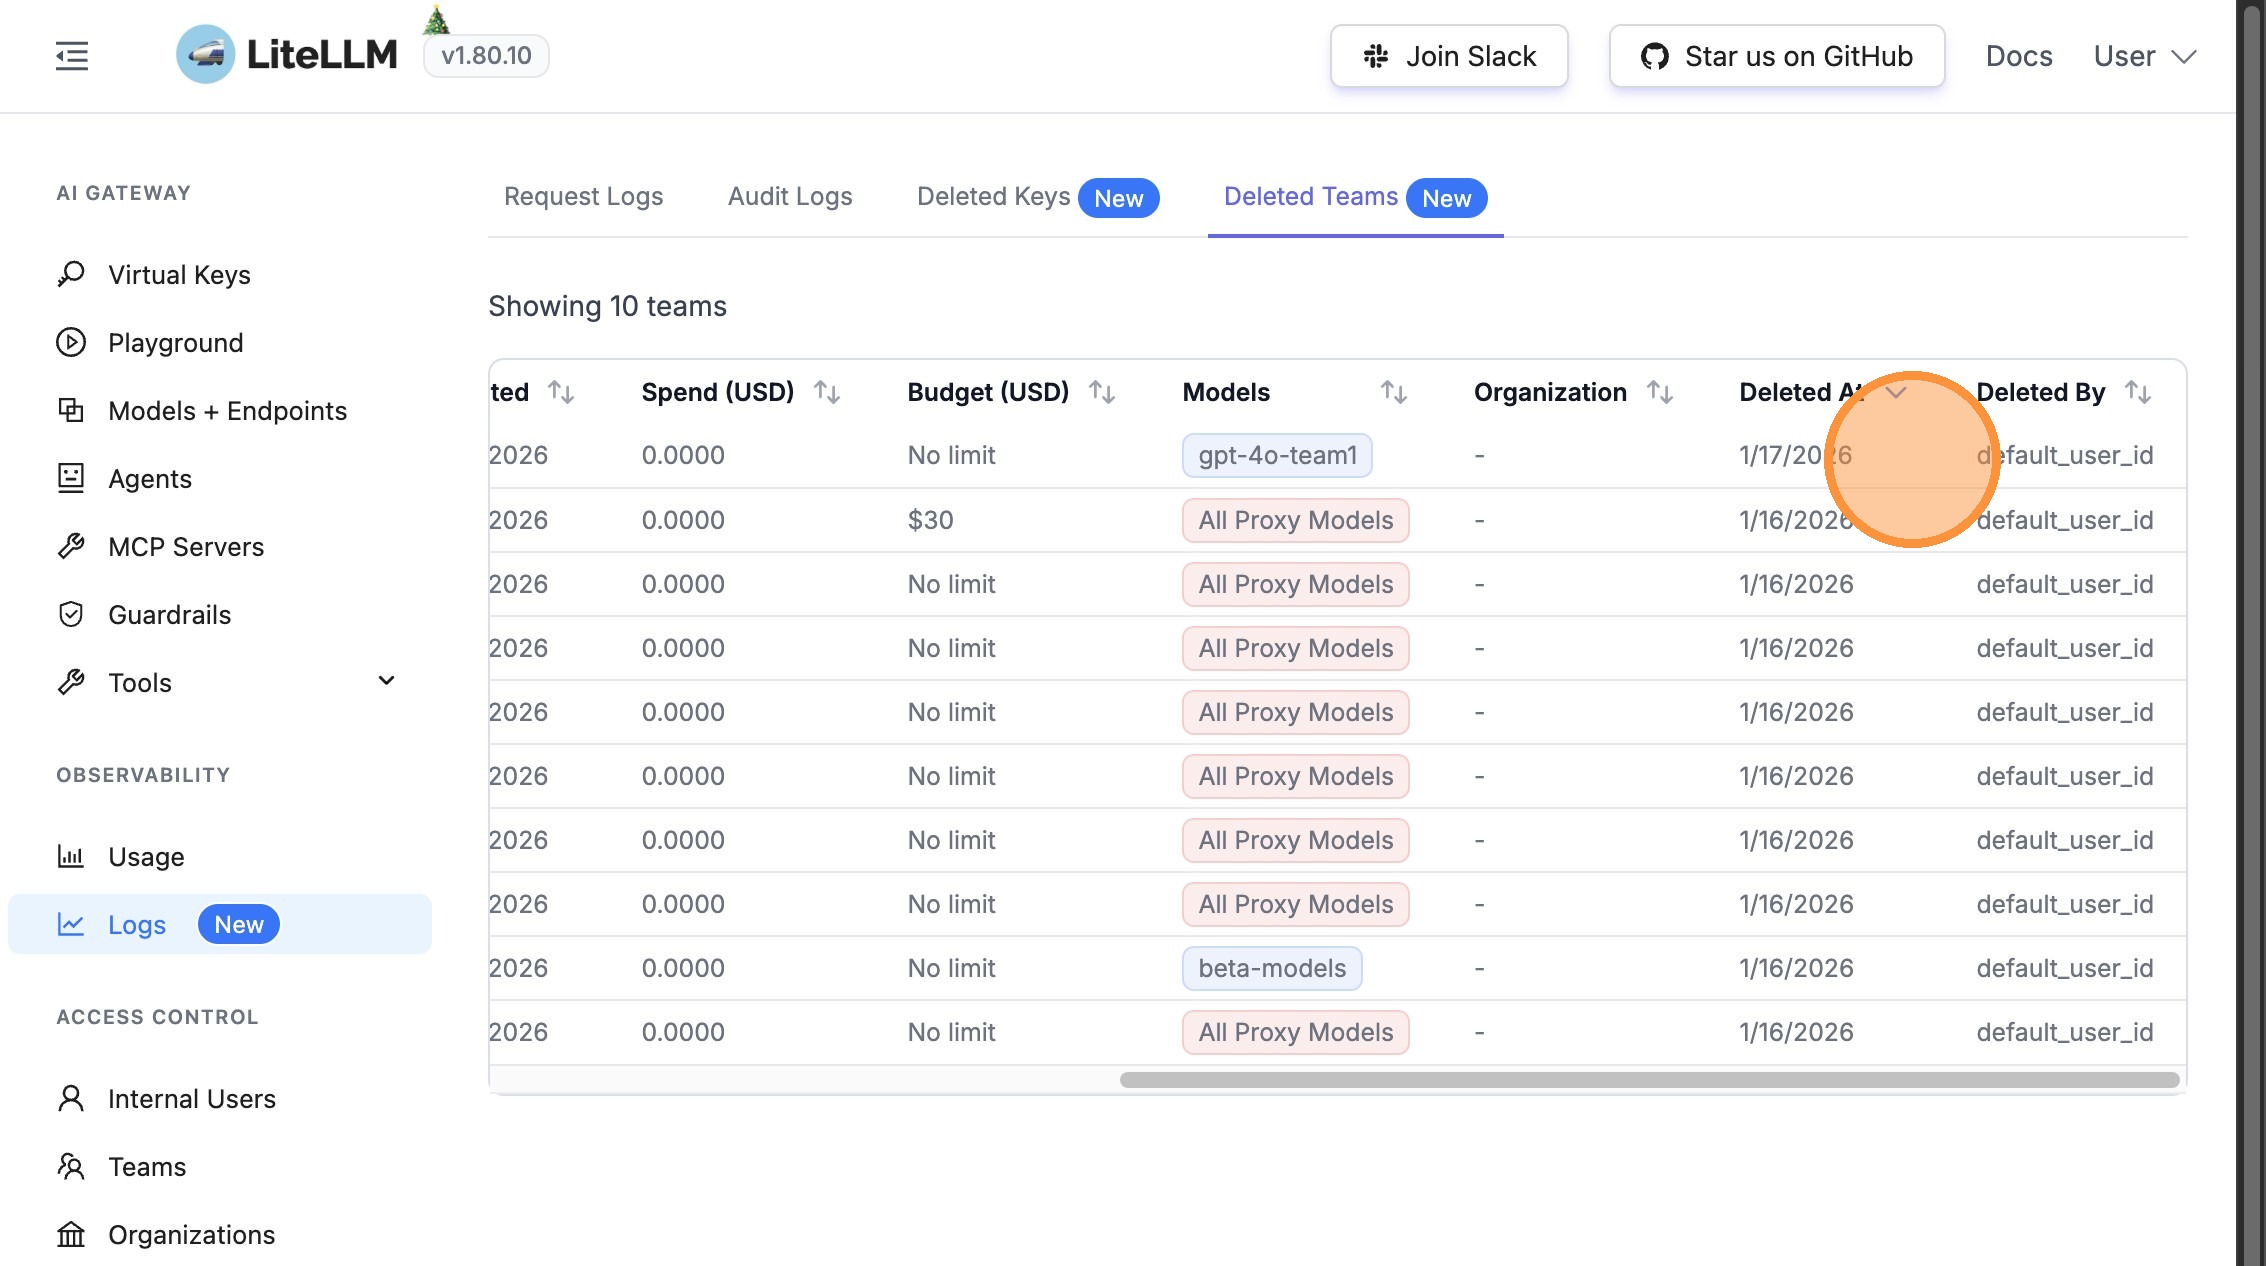
The Deleted Teams table provides detailed information about each deleted team:
|
||||
|
||||
- **When** the team was deleted (timestamp)
|
||||
- **Who** deleted the team (user/admin information)
|
||||
- **Team identification** details
|
||||
|
||||
|
||||
|
||||
### Step 3: View Team Financial Information
|
||||
|
||||
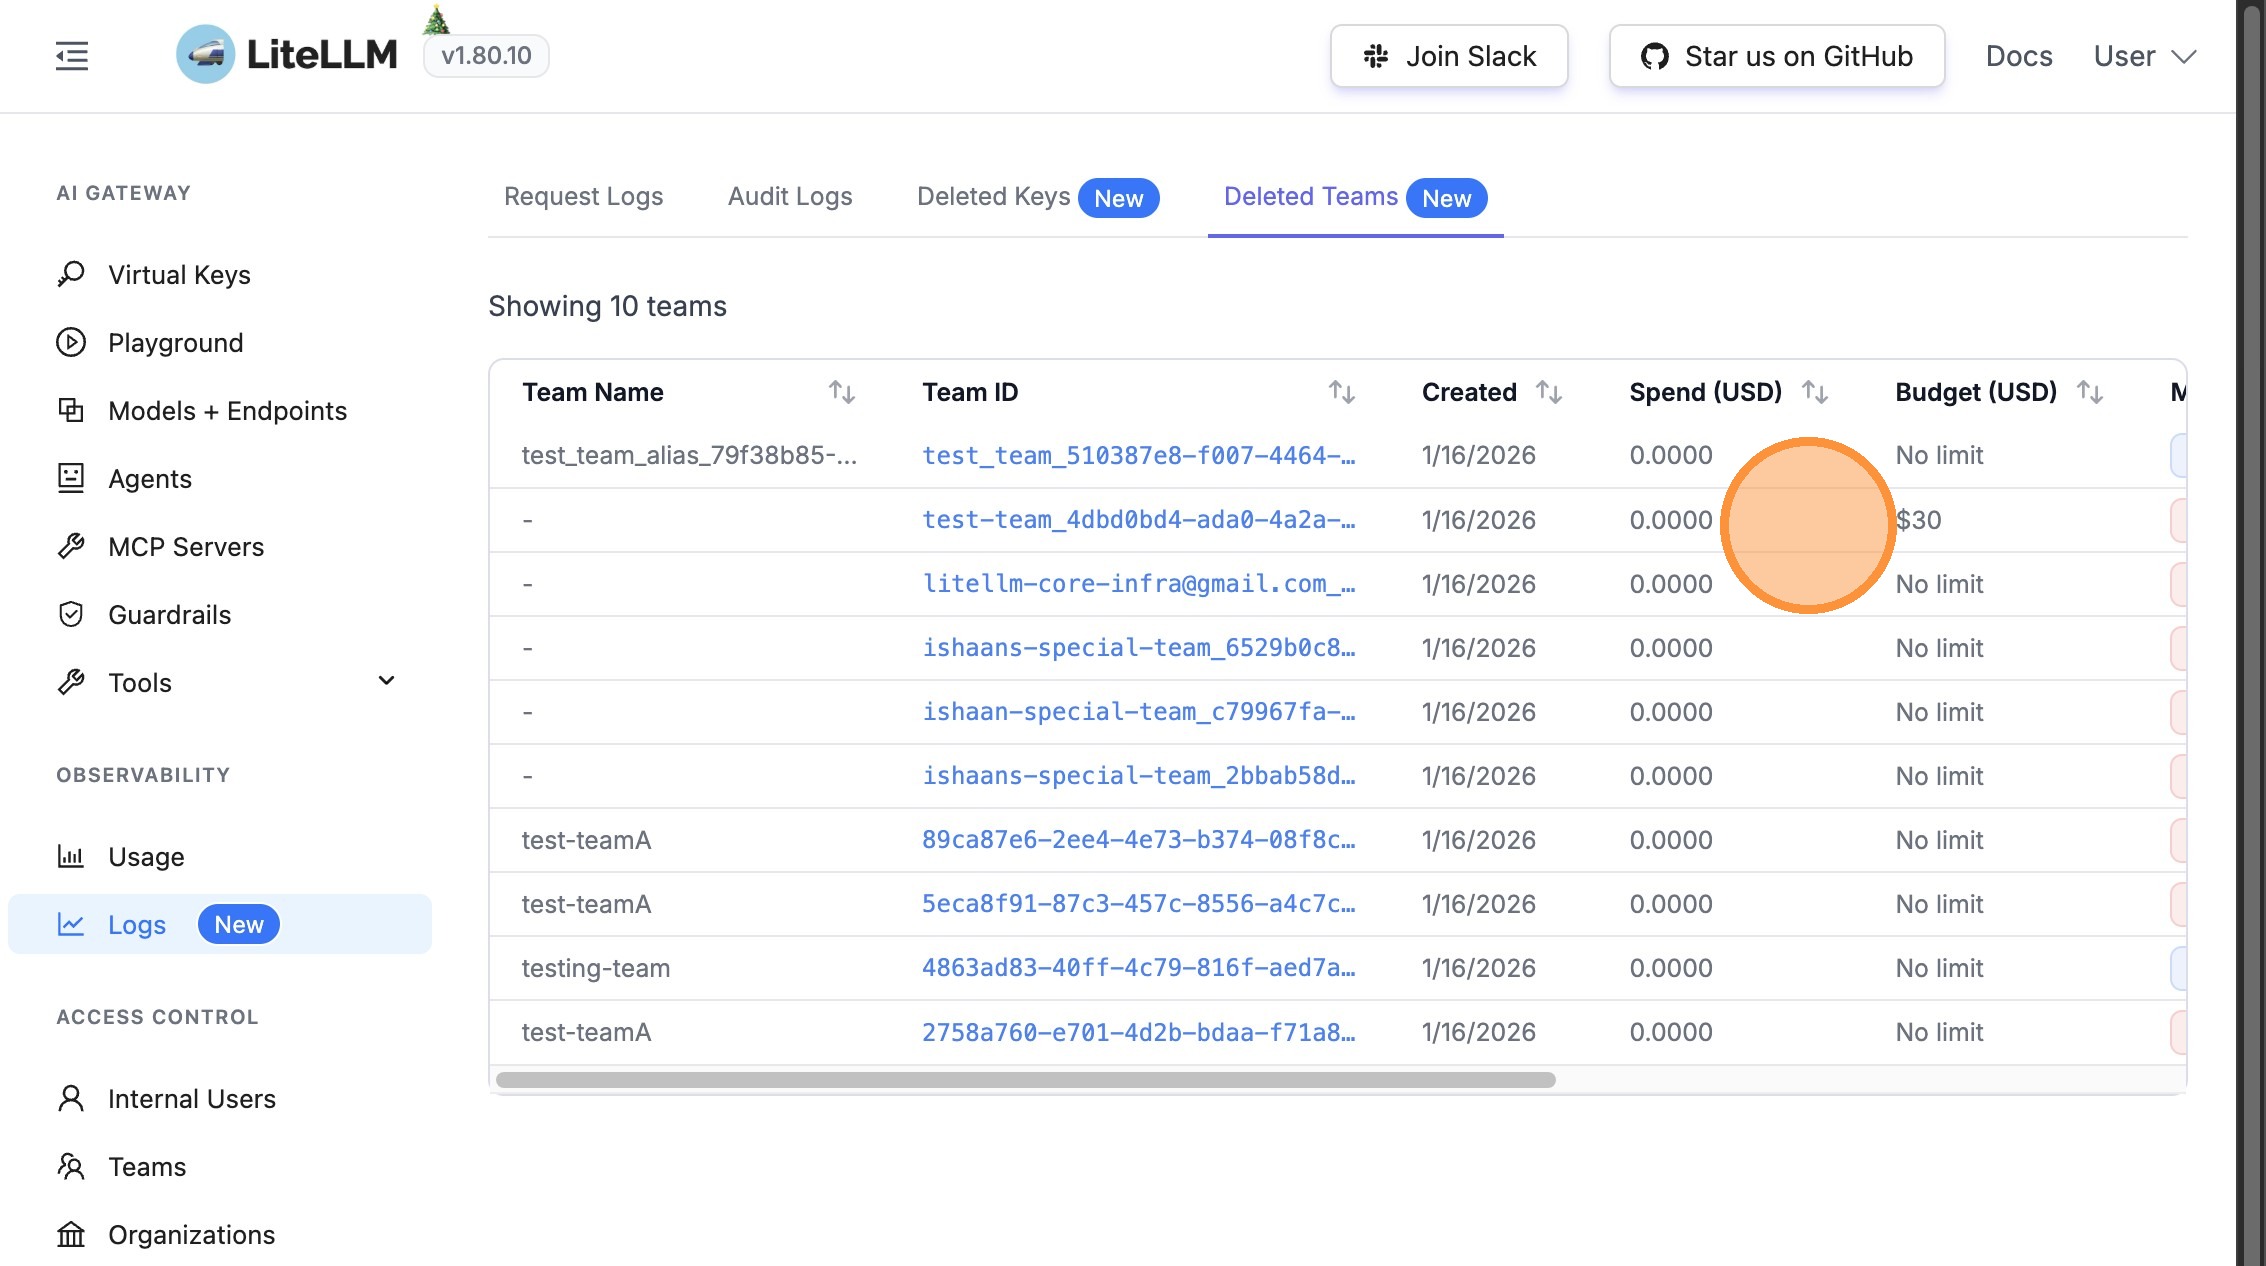
Similar to deleted keys, the Deleted Teams table shows financial information:
|
||||
|
||||
- **Spend at deletion** - Total spend accumulated when the team was deleted
|
||||
- **Original budget** - The budget limit that was set for the team
|
||||
|
||||
|
||||
|
||||
## Use Cases
|
||||
|
||||
This feature is particularly useful for:
|
||||
|
||||
- **Financial Auditing** - Track spend and budgets for deleted entities
|
||||
- **Compliance** - Maintain records of who deleted what and when
|
||||
- **Cost Analysis** - Understand spending patterns before deletion
|
||||
- **Accountability** - Identify which admin or user performed deletions
|
||||
- **Historical Records** - Preserve financial data even after entity deletion
|
||||
|
||||
## Related Features
|
||||
|
||||
- [Audit Logs](./multiple_admins.md) - View comprehensive audit logs for all entity changes
|
||||
- [UI Logs](./ui_logs.md) - View request logs and spend tracking
|
||||
|
|
@ -76,7 +76,7 @@ response = requests.post(
|
|||
print(response.json())
|
||||
```
|
||||
|
||||
### GET /fallback/{model}
|
||||
### GET /fallback/\{model\}
|
||||
|
||||
Get fallback configuration for a specific model.
|
||||
|
||||
|
|
@ -112,7 +112,7 @@ response = requests.get(
|
|||
print(response.json())
|
||||
```
|
||||
|
||||
### DELETE /fallback/{model}
|
||||
### DELETE /fallback/\{model\}
|
||||
|
||||
Delete fallback configuration for a specific model.
|
||||
|
||||
|
|
@ -150,9 +150,6 @@ print(response.json())
|
|||
|
||||
### Test fallback
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
```bash
|
||||
curl -X POST 'http://0.0.0.0:4000/chat/completions' \
|
||||
-H 'Content-Type: application/json' \
|
||||
|
|
@ -170,9 +167,6 @@ curl -X POST 'http://0.0.0.0:4000/chat/completions' \
|
|||
'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
||||
|
||||
## Validation
|
||||
|
|
|
|||
|
|
@ -206,6 +206,7 @@ Expected successful response:
|
|||
| `mode` | No | When to run the guardrail | `pre_call` |
|
||||
| `fallback_on_error` | No | Action when PANW API is unavailable: `"block"` (fail-closed, default) or `"allow"` (fail-open). Config errors always block. | `block` |
|
||||
| `timeout` | No | PANW API call timeout in seconds (1-60) | `10.0` |
|
||||
| `violation_message_template` | No | Custom template for error message when request is blocked. Supports `{guardrail_name}`, `{category}`, `{action_type}`, `{default_message}` placeholders. | - |
|
||||
|
||||
### Regional Endpoints
|
||||
|
||||
|
|
@ -449,6 +450,33 @@ LiteLLM does not alter or configure your PANW security profile. To change what c
|
|||
The guardrail is **fail-closed** by default - if the PANW API is unavailable, requests are blocked to ensure no unscanned content reaches your LLM. This provides maximum security.
|
||||
:::
|
||||
|
||||
### Custom Violation Messages
|
||||
|
||||
You can customize the error message returned to the user when a request is blocked by configuring the `violation_message_template` parameter. This is useful for providing user-friendly feedback instead of technical details.
|
||||
|
||||
```yaml
|
||||
guardrails:
|
||||
- guardrail_name: "panw-custom-message"
|
||||
litellm_params:
|
||||
guardrail: panw_prisma_airs
|
||||
api_key: os.environ/PANW_PRISMA_AIRS_API_KEY
|
||||
# Simple message
|
||||
violation_message_template: "Your request was blocked by our AI Security Policy."
|
||||
|
||||
- guardrail_name: "panw-detailed-message"
|
||||
litellm_params:
|
||||
guardrail: panw_prisma_airs
|
||||
api_key: os.environ/PANW_PRISMA_AIRS_API_KEY
|
||||
# Message with placeholders
|
||||
violation_message_template: "{action_type} blocked due to {category} violation. Please contact support."
|
||||
```
|
||||
|
||||
**Supported Placeholders:**
|
||||
- `{guardrail_name}`: Name of the guardrail (e.g. "panw-custom-message")
|
||||
- `{category}`: Violation category (e.g. "malicious", "injection", "dlp")
|
||||
- `{action_type}`: "Prompt" or "Response"
|
||||
- `{default_message}`: The original technical error message
|
||||
|
||||
### Fail-Open Configuration
|
||||
|
||||
By default, the PANW guardrail operates in **fail-closed** mode for maximum security. If the PANW API is unavailable (timeout, rate limit, network error), requests are blocked. You can configure **fail-open** mode for high-availability scenarios where service continuity is critical.
|
||||
|
|
|
|||
203
docs/my-website/docs/tutorials/claude_code_websearch.md
Normal file
203
docs/my-website/docs/tutorials/claude_code_websearch.md
Normal file
|
|
@ -0,0 +1,203 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Claude Code - WebSearch Across All Providers
|
||||
|
||||
Enable Claude Code's web search tool to work with any provider (Bedrock, Azure, Vertex, etc.). LiteLLM automatically intercepts web search requests and executes them server-side.
|
||||
|
||||
<Image img={require('../../img/claude_code_websearch.png')} />
|
||||
|
||||
## Proxy Configuration
|
||||
|
||||
Add WebSearch interception to your `litellm_config.yaml`:
|
||||
|
||||
```yaml showLineNumbers title="litellm_config.yaml"
|
||||
model_list:
|
||||
- model_name: bedrock-sonnet
|
||||
litellm_params:
|
||||
model: bedrock/us.anthropic.claude-sonnet-4-5-20250929-v1:0
|
||||
aws_region_name: us-east-1
|
||||
|
||||
# Enable WebSearch interception for providers
|
||||
litellm_settings:
|
||||
callbacks:
|
||||
- websearch_interception:
|
||||
enabled_providers:
|
||||
- bedrock
|
||||
- azure
|
||||
- vertex_ai
|
||||
search_tool_name: perplexity-search # Optional: specific search tool
|
||||
|
||||
# Configure search provider
|
||||
search_tools:
|
||||
- search_tool_name: perplexity-search
|
||||
litellm_params:
|
||||
search_provider: perplexity
|
||||
api_key: os.environ/PERPLEXITY_API_KEY
|
||||
```
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Configure LiteLLM Proxy
|
||||
|
||||
Create `config.yaml`:
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
model_list:
|
||||
- model_name: bedrock-sonnet
|
||||
litellm_params:
|
||||
model: bedrock/us.anthropic.claude-sonnet-4-5-20250929-v1:0
|
||||
aws_region_name: us-east-1
|
||||
|
||||
litellm_settings:
|
||||
callbacks:
|
||||
- websearch_interception:
|
||||
enabled_providers: [bedrock]
|
||||
|
||||
search_tools:
|
||||
- search_tool_name: perplexity-search
|
||||
litellm_params:
|
||||
search_provider: perplexity
|
||||
api_key: os.environ/PERPLEXITY_API_KEY
|
||||
```
|
||||
|
||||
### 2. Start Proxy
|
||||
|
||||
```bash showLineNumbers title="Start LiteLLM Proxy"
|
||||
export PERPLEXITY_API_KEY=your-key
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
### 3. Use with Claude Code
|
||||
|
||||
```bash showLineNumbers title="Configure Claude Code"
|
||||
export ANTHROPIC_BASE_URL=http://localhost:4000
|
||||
export ANTHROPIC_API_KEY=sk-1234
|
||||
claude
|
||||
```
|
||||
|
||||
Now use web search in Claude Code - it works with any provider!
|
||||
|
||||
## How It Works
|
||||
|
||||
When Claude Code sends a web search request, LiteLLM:
|
||||
1. Intercepts the native `web_search` tool
|
||||
2. Converts it to LiteLLM's standard format
|
||||
3. Executes the search via Perplexity/Tavily
|
||||
4. Returns the final answer to Claude Code
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant CC as Claude Code
|
||||
participant LP as LiteLLM Proxy
|
||||
participant B as Bedrock/Azure/etc
|
||||
participant P as Perplexity/Tavily
|
||||
|
||||
CC->>LP: Request with web_search tool
|
||||
Note over LP: Convert native tool<br/>to LiteLLM format
|
||||
LP->>B: Request with converted tool
|
||||
B-->>LP: Response: tool_use
|
||||
Note over LP: Detect web search<br/>tool_use
|
||||
LP->>P: Execute search
|
||||
P-->>LP: Search results
|
||||
LP->>B: Follow-up with results
|
||||
B-->>LP: Final answer
|
||||
LP-->>CC: Final answer with search results
|
||||
```
|
||||
|
||||
**Result**: One API call from Claude Code → Complete answer with search results
|
||||
|
||||
## Supported Providers
|
||||
|
||||
| Provider | Native Web Search | With LiteLLM |
|
||||
|----------|-------------------|--------------|
|
||||
| **Anthropic** | ✅ Yes | ✅ Yes |
|
||||
| **Bedrock** | ❌ No | ✅ Yes |
|
||||
| **Azure** | ❌ No | ✅ Yes |
|
||||
| **Vertex AI** | ❌ No | ✅ Yes |
|
||||
| **Other Providers** | ❌ No | ✅ Yes |
|
||||
|
||||
## Search Providers
|
||||
|
||||
Configure which search provider to use. LiteLLM supports multiple search providers:
|
||||
|
||||
| Provider | `search_provider` Value | Environment Variable |
|
||||
|----------|------------------------|----------------------|
|
||||
| **Perplexity AI** | `perplexity` | `PERPLEXITYAI_API_KEY` |
|
||||
| **Tavily** | `tavily` | `TAVILY_API_KEY` |
|
||||
| **Exa AI** | `exa_ai` | `EXA_API_KEY` |
|
||||
| **Parallel AI** | `parallel_ai` | `PARALLEL_AI_API_KEY` |
|
||||
| **Google PSE** | `google_pse` | `GOOGLE_PSE_API_KEY`, `GOOGLE_PSE_ENGINE_ID` |
|
||||
| **DataForSEO** | `dataforseo` | `DATAFORSEO_LOGIN`, `DATAFORSEO_PASSWORD` |
|
||||
| **Firecrawl** | `firecrawl` | `FIRECRAWL_API_KEY` |
|
||||
| **SearXNG** | `searxng` | `SEARXNG_API_BASE` (required) |
|
||||
| **Linkup** | `linkup` | `LINKUP_API_KEY` |
|
||||
|
||||
See [all supported search providers](../search/index.md) for detailed setup instructions and provider-specific parameters.
|
||||
|
||||
## Configuration Options
|
||||
|
||||
### WebSearch Interception Parameters
|
||||
|
||||
| Parameter | Type | Required | Description | Example |
|
||||
|-----------|------|----------|-------------|---------|
|
||||
| `enabled_providers` | List[String] | Yes | List of providers to enable web search interception for | `[bedrock, azure, vertex_ai]` |
|
||||
| `search_tool_name` | String | No | Specific search tool from `search_tools` config. If not set, uses first available search tool. | `perplexity-search` |
|
||||
|
||||
### Supported Provider Values
|
||||
|
||||
Use these values in `enabled_providers`:
|
||||
|
||||
| Provider | Value | Description |
|
||||
|----------|-------|-------------|
|
||||
| AWS Bedrock | `bedrock` | Amazon Bedrock Claude models |
|
||||
| Azure OpenAI | `azure` | Azure-hosted models |
|
||||
| Google Vertex AI | `vertex_ai` | Google Cloud Vertex AI |
|
||||
| Any Other | Provider name | Any LiteLLM-supported provider |
|
||||
|
||||
### Complete Configuration Example
|
||||
|
||||
```yaml showLineNumbers title="Complete config.yaml"
|
||||
model_list:
|
||||
- model_name: bedrock-sonnet
|
||||
litellm_params:
|
||||
model: bedrock/us.anthropic.claude-sonnet-4-5-20250929-v1:0
|
||||
aws_region_name: us-east-1
|
||||
|
||||
- model_name: azure-gpt4
|
||||
litellm_params:
|
||||
model: azure/gpt-4
|
||||
api_base: https://my-azure.openai.azure.com
|
||||
api_key: os.environ/AZURE_API_KEY
|
||||
|
||||
litellm_settings:
|
||||
callbacks:
|
||||
- websearch_interception:
|
||||
enabled_providers:
|
||||
- bedrock # Enable for AWS Bedrock
|
||||
- azure # Enable for Azure OpenAI
|
||||
- vertex_ai # Enable for Google Vertex
|
||||
search_tool_name: perplexity-search # Optional: use specific search tool
|
||||
|
||||
# Configure search tools
|
||||
search_tools:
|
||||
- search_tool_name: perplexity-search
|
||||
litellm_params:
|
||||
search_provider: perplexity
|
||||
api_key: os.environ/PERPLEXITY_API_KEY
|
||||
|
||||
- search_tool_name: tavily-search
|
||||
litellm_params:
|
||||
search_provider: tavily
|
||||
api_key: os.environ/TAVILY_API_KEY
|
||||
```
|
||||
|
||||
**How search tool selection works:**
|
||||
- If `search_tool_name` is specified → Uses that specific search tool
|
||||
- If `search_tool_name` is not specified → Uses first search tool in `search_tools` list
|
||||
- In example above: Without `search_tool_name`, would use `perplexity-search` (first in list)
|
||||
|
||||
## Related
|
||||
|
||||
- [Claude Code Quickstart](./claude_responses_api.md)
|
||||
- [Claude Code Cost Tracking](./claude_code_customer_tracking.md)
|
||||
- [Using Non-Anthropic Models](./claude_non_anthropic_models.md)
|
||||
|
|
@ -1,3 +1,5 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Cursor Integration
|
||||
|
||||
Route Cursor IDE requests through LiteLLM for unified logging, budget controls, and access to any model.
|
||||
|
|
@ -76,6 +78,34 @@ Send a message. All requests now route through LiteLLM.
|
|||
|
||||
---
|
||||
|
||||
## Connecting MCP Servers
|
||||
|
||||
You can also connect MCP servers to Cursor via LiteLLM Proxy.
|
||||
|
||||
For official instructions on configuring MCP integration with Cursor, please refer to the Cursor documentation here: [https://cursor.com/en-US/docs/context/mcp](https://cursor.com/en-US/docs/context/mcp).
|
||||
|
||||
1. In Cursor Settings, go to the "Tools & MCP" tab and click "New MCP Server".
|
||||
|
||||
2. In your `mcp.json`, add the following configuration:
|
||||
|
||||
```
|
||||
{
|
||||
"mcpServers": {
|
||||
"litellm": {
|
||||
"url": "http://localhost:4000/everything/mcp",
|
||||
"type": "http",
|
||||
"headers": {
|
||||
"Authorization": "Bearer sk-LITELLM_VIRTUAL_KEY"
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
3. LiteLLM's MCP will now appear under "Installed MCP Servers" in Cursor.
|
||||
|
||||
<Image img={require('../../img/cursor_mcp_installed.png')} />
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
| Issue | Solution |
|
||||
|
|
|
|||
BIN
docs/my-website/img/claude_code_websearch.png
Normal file
BIN
docs/my-website/img/claude_code_websearch.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 7.4 MiB |
BIN
docs/my-website/img/cursor_mcp_installed.png
Normal file
BIN
docs/my-website/img/cursor_mcp_installed.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 125 KiB |
BIN
docs/my-website/img/release_notes/claude_code_websearch.png
Normal file
BIN
docs/my-website/img/release_notes/claude_code_websearch.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 1.4 MiB |
BIN
docs/my-website/img/ui_deleted_keys_table.png
Normal file
BIN
docs/my-website/img/ui_deleted_keys_table.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 360 KiB |

Binary file not shown.
|
Before Width: | Height: | Size: 503 KiB After Width: | Height: | Size: 504 KiB |
|
|
@ -1,5 +1,5 @@
|
|||
---
|
||||
title: "[Preview] v1.80.15.rc.1 - Manus API Support"
|
||||
title: "v1.80.15-stable - Manus API Support"
|
||||
slug: "v1-80-15"
|
||||
date: 2026-01-10T10:00:00
|
||||
authors:
|
||||
|
|
@ -27,7 +27,7 @@ import TabItem from '@theme/TabItem';
|
|||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
docker.litellm.ai/berriai/litellm:v1.80.15.rc.1
|
||||
docker.litellm.ai/berriai/litellm:v1.80.15-stable.1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
|
@ -638,6 +638,6 @@ Users can now see Endpoint Activity Metrics in the UI.
|
|||
|
||||
## Full Changelog
|
||||
|
||||
**[View complete changelog on GitHub](https://github.com/BerriAI/litellm/compare/v1.80.11.rc.1...v1.80.14.rc.1)**
|
||||
**[View complete changelog on GitHub](https://github.com/BerriAI/litellm/compare/v1.80.11.rc.1...v1.80.15-stable.1)**
|
||||
|
||||
|
||||
|
|
|
|||
517
docs/my-website/release_notes/v1.81.0/index.md
Normal file
517
docs/my-website/release_notes/v1.81.0/index.md
Normal file
|
|
@ -0,0 +1,517 @@
|
|||
---
|
||||
title: "v1.81.0 - Claude Code - Web Search Across All Providers"
|
||||
slug: "v1-81-0"
|
||||
date: 2026-01-18T10:00:00
|
||||
authors:
|
||||
- name: Krrish Dholakia
|
||||
title: CEO, LiteLLM
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: CTO, LiteLLM
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Image from '@theme/IdealImage';
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
## Deploy this version
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="docker" label="Docker">
|
||||
|
||||
``` showLineNumbers title="docker run litellm"
|
||||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
docker.litellm.ai/berriai/litellm:v1.81.0
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="pip" label="Pip">
|
||||
|
||||
``` showLineNumbers title="pip install litellm"
|
||||
pip install litellm==1.81.0
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
---
|
||||
|
||||
## Key Highlights
|
||||
|
||||
- **Claude Code** - Support for using web search across Bedrock, Vertex AI, and all LiteLLM providers
|
||||
- **Major Change** - [50MB limit on image URL downloads](#major-change---chatcompletions-image-url-download-size-limit) to improve reliability
|
||||
- **Performance** - [25% CPU Usage Reduction](#performance---25-cpu-usage-reduction) by removing premature model.dump() calls from the hot path
|
||||
- **Deleted Keys Audit Table on UI** - [View deleted keys and teams for audit purposes](../../docs/proxy/deleted_keys_teams.md) with spend and budget information at the time of deletion
|
||||
|
||||
---
|
||||
|
||||
## Claude Code - Web Search Across All Providers
|
||||
|
||||
<Image img={require('../../img/release_notes/claude_code_websearch.png')} />
|
||||
|
||||
This release brings web search support to Claude Code across all LiteLLM providers (Bedrock, Azure, Vertex AI, and more), enabling AI coding assistants to search the web for real-time information.
|
||||
|
||||
This means you can now use Claude Code's web search tool with any provider, not just Anthropic's native API. LiteLLM automatically intercepts web search requests and executes them server-side using your configured search provider (Perplexity, Tavily, Exa AI, and more).
|
||||
|
||||
Proxy Admins can configure web search interception in their LiteLLM proxy config to enable this capability for their teams using Claude Code with Bedrock, Azure, or any other supported provider.
|
||||
|
||||
[**Learn more →**](../../docs/tutorials/claude_code_websearch.md)
|
||||
|
||||
---
|
||||
|
||||
## Major Change - /chat/completions Image URL Download Size Limit
|
||||
|
||||
To improve reliability and prevent memory issues, LiteLLM now includes a configurable **50MB limit** on image URL downloads by default. Previously, there was no limit on image downloads, which could occasionally cause memory issues with very large images.
|
||||
|
||||
### How It Works
|
||||
|
||||
Requests with image URLs exceeding 50MB will receive a helpful error message:
|
||||
|
||||
```bash
|
||||
curl -X POST 'https://your-litellm-proxy.com/chat/completions' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-d '{
|
||||
"model": "gpt-4o",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "text",
|
||||
"text": "What is in this image?"
|
||||
},
|
||||
{
|
||||
"type": "image_url",
|
||||
"image_url": {
|
||||
"url": "https://example.com/very-large-image.jpg"
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
**Error Response:**
|
||||
|
||||
```json
|
||||
{
|
||||
"error": {
|
||||
"message": "Error: Image size (75.50MB) exceeds maximum allowed size (50.0MB). url=https://example.com/very-large-image.jpg",
|
||||
"type": "ImageFetchError"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Configuring the Limit
|
||||
|
||||
The default 50MB limit works well for most use cases, but you can easily adjust it if needed:
|
||||
|
||||
**Increase the limit (e.g., to 100MB):**
|
||||
|
||||
```bash
|
||||
export MAX_IMAGE_URL_DOWNLOAD_SIZE_MB=100
|
||||
```
|
||||
|
||||
**Disable image URL downloads (for security):**
|
||||
|
||||
```bash
|
||||
export MAX_IMAGE_URL_DOWNLOAD_SIZE_MB=0
|
||||
```
|
||||
|
||||
**Docker Configuration:**
|
||||
|
||||
```bash
|
||||
docker run \
|
||||
-e MAX_IMAGE_URL_DOWNLOAD_SIZE_MB=100 \
|
||||
-p 4000:4000 \
|
||||
docker.litellm.ai/berriai/litellm:v1.81.0
|
||||
```
|
||||
|
||||
**Proxy Config (config.yaml):**
|
||||
|
||||
```yaml
|
||||
general_settings:
|
||||
master_key: sk-1234
|
||||
|
||||
# Set via environment variable
|
||||
environment_variables:
|
||||
MAX_IMAGE_URL_DOWNLOAD_SIZE_MB: "100"
|
||||
```
|
||||
|
||||
### Why Add This?
|
||||
|
||||
This feature improves reliability by:
|
||||
- Preventing memory issues from very large images
|
||||
- Aligning with OpenAI's 50MB payload limit
|
||||
- Validating image sizes early (when Content-Length header is available)
|
||||
|
||||
---
|
||||
|
||||
## Performance - 25% CPU Usage Reduction
|
||||
|
||||
LiteLLM now reduces CPU usage by removing premature `model.dump()` calls from the hot path in request processing. Previously, Pydantic model serialization was performed earlier and more frequently than necessary, causing unnecessary CPU overhead on every request. By deferring serialization until it is actually needed, LiteLLM reduces CPU usage and improves request throughput under high load.
|
||||
|
||||
---
|
||||
|
||||
## Deleted Keys Audit Table on UI
|
||||
|
||||
<Image img={require('../../img/ui_deleted_keys_table.png')} />
|
||||
|
||||
LiteLLM now provides a comprehensive audit table for deleted API keys and teams directly in the UI. This feature allows you to easily track the spend of deleted keys, view their associated team information, and maintain accurate financial records for auditing and compliance purposes. The table displays key details including key aliases, team associations, and spend information captured at the time of deletion. For more information on how to use this feature, see the [Deleted Keys & Teams documentation](../../docs/proxy/deleted_keys_teams.md).
|
||||
|
||||
---
|
||||
|
||||
## New Models / Updated Models
|
||||
|
||||
#### New Model Support
|
||||
|
||||
| Provider | Model | Features |
|
||||
| -------- | ----- | -------- |
|
||||
| OpenAI | `gpt-5.2-codex` | Code generation |
|
||||
| Azure | `azure/gpt-5.2-codex` | Code generation |
|
||||
| Cerebras | `cerebras/zai-glm-4.7` | Reasoning, function calling |
|
||||
| Replicate | All chat models | Full support for all Replicate chat models |
|
||||
|
||||
#### Features
|
||||
|
||||
- **[Anthropic](../../docs/providers/anthropic)**
|
||||
- Add missing anthropic tool results in response - [PR #18945](https://github.com/BerriAI/litellm/pull/18945)
|
||||
- Preserve web_fetch_tool_result in multi-turn conversations - [PR #18142](https://github.com/BerriAI/litellm/pull/18142)
|
||||
|
||||
- **[Gemini](../../docs/providers/gemini)**
|
||||
- Add presence_penalty support for Google AI Studio - [PR #18154](https://github.com/BerriAI/litellm/pull/18154)
|
||||
- Forward extra_headers in generateContent adapter - [PR #18935](https://github.com/BerriAI/litellm/pull/18935)
|
||||
- Add medium value support for detail param - [PR #19187](https://github.com/BerriAI/litellm/pull/19187)
|
||||
|
||||
- **[Vertex AI](../../docs/providers/vertex)**
|
||||
- Improve passthrough endpoint URL parsing and construction - [PR #17526](https://github.com/BerriAI/litellm/pull/17526)
|
||||
- Add type object to tool schemas missing type field - [PR #19103](https://github.com/BerriAI/litellm/pull/19103)
|
||||
- Keep type field in Gemini schema when properties is empty - [PR #18979](https://github.com/BerriAI/litellm/pull/18979)
|
||||
|
||||
- **[Bedrock](../../docs/providers/bedrock)**
|
||||
- Add OpenAI-compatible service_tier parameter translation - [PR #18091](https://github.com/BerriAI/litellm/pull/18091)
|
||||
- Add user auth in standard logging object for Bedrock passthrough - [PR #19140](https://github.com/BerriAI/litellm/pull/19140)
|
||||
- Strip throughput tier suffixes from model names - [PR #19147](https://github.com/BerriAI/litellm/pull/19147)
|
||||
|
||||
- **[OCI](../../docs/providers/oci)**
|
||||
- Handle OpenAI-style image_url object in multimodal messages - [PR #18272](https://github.com/BerriAI/litellm/pull/18272)
|
||||
|
||||
- **[Ollama](../../docs/providers/ollama)**
|
||||
- Set finish_reason to tool_calls and remove broken capability check - [PR #18924](https://github.com/BerriAI/litellm/pull/18924)
|
||||
|
||||
- **[Watsonx](../../docs/providers/watsonx/index)**
|
||||
- Allow passing scope ID for Watsonx inferencing - [PR #18959](https://github.com/BerriAI/litellm/pull/18959)
|
||||
|
||||
- **[Replicate](../../docs/providers/replicate)**
|
||||
- Add all chat Replicate models support - [PR #18954](https://github.com/BerriAI/litellm/pull/18954)
|
||||
|
||||
- **[OpenRouter](../../docs/providers/openrouter)**
|
||||
- Add OpenRouter support for image/generation endpoints - [PR #19059](https://github.com/BerriAI/litellm/pull/19059)
|
||||
|
||||
- **[Volcengine](../../docs/providers/volcano)**
|
||||
- Add max_tokens settings for Volcengine models (deepseek-v3-2, glm-4-7, kimi-k2-thinking) - [PR #19076](https://github.com/BerriAI/litellm/pull/19076)
|
||||
|
||||
- **Azure Model Router**
|
||||
- New Model - Azure Model Router on LiteLLM AI Gateway - [PR #19054](https://github.com/BerriAI/litellm/pull/19054)
|
||||
|
||||
- **GPT-5 Models**
|
||||
- Correct context window sizes for GPT-5 model variants - [PR #18928](https://github.com/BerriAI/litellm/pull/18928)
|
||||
- Correct max_input_tokens for GPT-5 models - [PR #19056](https://github.com/BerriAI/litellm/pull/19056)
|
||||
|
||||
- **Text Completion**
|
||||
- Support token IDs (list of integers) as prompt - [PR #18011](https://github.com/BerriAI/litellm/pull/18011)
|
||||
|
||||
### Bug Fixes
|
||||
|
||||
- **[Anthropic](../../docs/providers/anthropic)**
|
||||
- Prevent dropping thinking when any message has thinking_blocks - [PR #18929](https://github.com/BerriAI/litellm/pull/18929)
|
||||
- Fix anthropic token counter with thinking - [PR #19067](https://github.com/BerriAI/litellm/pull/19067)
|
||||
- Add better error handling for Anthropic - [PR #18955](https://github.com/BerriAI/litellm/pull/18955)
|
||||
- Fix Anthropic during call error - [PR #19060](https://github.com/BerriAI/litellm/pull/19060)
|
||||
|
||||
- **[Gemini](../../docs/providers/gemini)**
|
||||
- Fix missing `completion_tokens_details` in Gemini 3 Flash when reasoning_effort is not used - [PR #18898](https://github.com/BerriAI/litellm/pull/18898)
|
||||
- Fix Gemini Image Generation imageConfig parameters - [PR #18948](https://github.com/BerriAI/litellm/pull/18948)
|
||||
|
||||
- **[Vertex AI](../../docs/providers/vertex)**
|
||||
- Fix Vertex AI 400 Error with CachedContent model mismatch - [PR #19193](https://github.com/BerriAI/litellm/pull/19193)
|
||||
- Fix Vertex AI doesn't support structured output - [PR #19201](https://github.com/BerriAI/litellm/pull/19201)
|
||||
|
||||
- **[Bedrock](../../docs/providers/bedrock)**
|
||||
- Fix Claude Code (`/messages`) Bedrock Invoke usage and request signing - [PR #19111](https://github.com/BerriAI/litellm/pull/19111)
|
||||
- Fix model ID encoding for Bedrock passthrough - [PR #18944](https://github.com/BerriAI/litellm/pull/18944)
|
||||
- Respect max_completion_tokens in thinking feature - [PR #18946](https://github.com/BerriAI/litellm/pull/18946)
|
||||
- Fix header forwarding in Bedrock passthrough - [PR #19007](https://github.com/BerriAI/litellm/pull/19007)
|
||||
- Fix Bedrock stability model usage issues - [PR #19199](https://github.com/BerriAI/litellm/pull/19199)
|
||||
|
||||
---
|
||||
|
||||
## LLM API Endpoints
|
||||
|
||||
#### Features
|
||||
|
||||
- **[/messages (Claude Code)](../../docs/providers/anthropic)**
|
||||
- Add support for Tool Search on `/messages` API across Azure, Bedrock, and Anthropic API - [PR #19165](https://github.com/BerriAI/litellm/pull/19165)
|
||||
- Track end-users with Claude Code (`/messages`) for better analytics and monitoring - [PR #19171](https://github.com/BerriAI/litellm/pull/19171)
|
||||
- Add web search support using LiteLLM `/search` endpoint with Claude Code (`/messages`) - [PR #19263](https://github.com/BerriAI/litellm/pull/19263), [PR #19294](https://github.com/BerriAI/litellm/pull/19294)
|
||||
|
||||
- **[/messages (Claude Code) - Bedrock](../../docs/providers/bedrock)**
|
||||
- Add support for Prompt Caching with Bedrock Converse on `/messages` - [PR #19123](https://github.com/BerriAI/litellm/pull/19123)
|
||||
- Ensure budget tokens are passed to Bedrock Converse API correctly on `/messages` - [PR #19107](https://github.com/BerriAI/litellm/pull/19107)
|
||||
|
||||
- **[Responses API](../../docs/response_api)**
|
||||
- Add support for caching for responses API - [PR #19068](https://github.com/BerriAI/litellm/pull/19068)
|
||||
- Add retry policy support to responses API - [PR #19074](https://github.com/BerriAI/litellm/pull/19074)
|
||||
|
||||
- **Realtime API**
|
||||
- Use non-streaming method for endpoint v1/a2a/message/send - [PR #19025](https://github.com/BerriAI/litellm/pull/19025)
|
||||
|
||||
- **Batch API**
|
||||
- Fix batch deletion and retrieve - [PR #18340](https://github.com/BerriAI/litellm/pull/18340)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- **General**
|
||||
- Fix responses content can't be none - [PR #19064](https://github.com/BerriAI/litellm/pull/19064)
|
||||
- Fix model name from query param in realtime request - [PR #19135](https://github.com/BerriAI/litellm/pull/19135)
|
||||
- Fix video status/content credential injection for wildcard models - [PR #18854](https://github.com/BerriAI/litellm/pull/18854)
|
||||
|
||||
---
|
||||
|
||||
## Management Endpoints / UI
|
||||
|
||||
#### Features
|
||||
|
||||
**Virtual Keys**
|
||||
- View deleted keys for audit purposes - [PR #18228](https://github.com/BerriAI/litellm/pull/18228), [PR #19268](https://github.com/BerriAI/litellm/pull/19268)
|
||||
- Add status query parameter for keys list - [PR #19260](https://github.com/BerriAI/litellm/pull/19260)
|
||||
- Refetch keys after key creation - [PR #18994](https://github.com/BerriAI/litellm/pull/18994)
|
||||
- Refresh keys list on delete - [PR #19262](https://github.com/BerriAI/litellm/pull/19262)
|
||||
- Simplify key generate permission error - [PR #18997](https://github.com/BerriAI/litellm/pull/18997)
|
||||
- Add search to key edit team dropdown - [PR #19119](https://github.com/BerriAI/litellm/pull/19119)
|
||||
|
||||
**Teams & Organizations**
|
||||
- View deleted teams for audit purposes - [PR #18228](https://github.com/BerriAI/litellm/pull/18228), [PR #19268](https://github.com/BerriAI/litellm/pull/19268)
|
||||
- Add filters to organization table - [PR #18916](https://github.com/BerriAI/litellm/pull/18916)
|
||||
- Add query parameters to `/organization/list` - [PR #18910](https://github.com/BerriAI/litellm/pull/18910)
|
||||
- Add status query parameter for teams list - [PR #19260](https://github.com/BerriAI/litellm/pull/19260)
|
||||
- Show internal users their spend only - [PR #19227](https://github.com/BerriAI/litellm/pull/19227)
|
||||
- Allow preventing team admins from deleting members from teams - [PR #19128](https://github.com/BerriAI/litellm/pull/19128)
|
||||
- Refactor team member icon buttons - [PR #19192](https://github.com/BerriAI/litellm/pull/19192)
|
||||
|
||||
**Models + Endpoints**
|
||||
- Display health information in public model hub - [PR #19256](https://github.com/BerriAI/litellm/pull/19256), [PR #19258](https://github.com/BerriAI/litellm/pull/19258)
|
||||
- Quality of life improvements for Anthropic models - [PR #19058](https://github.com/BerriAI/litellm/pull/19058)
|
||||
- Create reusable model select component - [PR #19164](https://github.com/BerriAI/litellm/pull/19164)
|
||||
- Edit settings model dropdown - [PR #19186](https://github.com/BerriAI/litellm/pull/19186)
|
||||
- Fix model hub client side exception - [PR #19045](https://github.com/BerriAI/litellm/pull/19045)
|
||||
|
||||
**Usage & Analytics**
|
||||
- Allow top virtual keys and models to show more entries - [PR #19050](https://github.com/BerriAI/litellm/pull/19050)
|
||||
- Fix Y axis on model activity chart - [PR #19055](https://github.com/BerriAI/litellm/pull/19055)
|
||||
- Add Team ID and Team Name in export report - [PR #19047](https://github.com/BerriAI/litellm/pull/19047)
|
||||
- Add user metrics for Prometheus - [PR #18785](https://github.com/BerriAI/litellm/pull/18785)
|
||||
|
||||
**SSO & Auth**
|
||||
- Allow setting custom MSFT Base URLs - [PR #18977](https://github.com/BerriAI/litellm/pull/18977)
|
||||
- Allow overriding env var attribute names - [PR #18998](https://github.com/BerriAI/litellm/pull/18998)
|
||||
- Fix SCIM GET /Users error and enforce SCIM 2.0 compliance - [PR #17420](https://github.com/BerriAI/litellm/pull/17420)
|
||||
- Feature flag for SCIM compliance fix - [PR #18878](https://github.com/BerriAI/litellm/pull/18878)
|
||||
|
||||
**General UI**
|
||||
- Add allowClear to dropdown components for better UX - [PR #18778](https://github.com/BerriAI/litellm/pull/18778)
|
||||
- Add community engagement buttons - [PR #19114](https://github.com/BerriAI/litellm/pull/19114)
|
||||
- UI Feedback Form - why LiteLLM - [PR #18999](https://github.com/BerriAI/litellm/pull/18999)
|
||||
- Refactor user and team table filters to reusable component - [PR #19010](https://github.com/BerriAI/litellm/pull/19010)
|
||||
- Adjusting new badges - [PR #19278](https://github.com/BerriAI/litellm/pull/19278)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- Container API routes return 401 for non-admin users - routes missing from openai_routes - [PR #19115](https://github.com/BerriAI/litellm/pull/19115)
|
||||
- Allow routing to regional endpoints for Containers API - [PR #19118](https://github.com/BerriAI/litellm/pull/19118)
|
||||
- Fix Azure Storage circular reference error - [PR #19120](https://github.com/BerriAI/litellm/pull/19120)
|
||||
- Fix prompt deletion fails with Prisma FieldNotFoundError - [PR #18966](https://github.com/BerriAI/litellm/pull/18966)
|
||||
|
||||
---
|
||||
|
||||
## AI Integrations
|
||||
|
||||
### Logging
|
||||
|
||||
- **[OpenTelemetry](../../docs/proxy/logging#opentelemetry)**
|
||||
- Update semantic conventions to 1.38 (gen_ai attributes) - [PR #18793](https://github.com/BerriAI/litellm/pull/18793)
|
||||
|
||||
- **[LangSmith](../../docs/proxy/logging#langsmith)**
|
||||
- Hoist thread grouping metadata (session_id, thread) - [PR #18982](https://github.com/BerriAI/litellm/pull/18982)
|
||||
|
||||
- **[Langfuse](../../docs/proxy/logging#langfuse)**
|
||||
- Include Langfuse logger in JSON logging when Langfuse callback is used - [PR #19162](https://github.com/BerriAI/litellm/pull/19162)
|
||||
|
||||
- **[Logfire](../../docs/observability/logfire)**
|
||||
- Add ability to customize Logfire base URL through env var - [PR #19148](https://github.com/BerriAI/litellm/pull/19148)
|
||||
|
||||
- **General Logging**
|
||||
- Enable JSON logging via configuration and add regression test - [PR #19037](https://github.com/BerriAI/litellm/pull/19037)
|
||||
- Fix header forwarding for embeddings endpoint - [PR #18960](https://github.com/BerriAI/litellm/pull/18960)
|
||||
- Preserve llm_provider-* headers in error responses - [PR #19020](https://github.com/BerriAI/litellm/pull/19020)
|
||||
- Fix turn_off_message_logging not redacting request messages in proxy_server_request field - [PR #18897](https://github.com/BerriAI/litellm/pull/18897)
|
||||
|
||||
### Guardrails
|
||||
|
||||
- **[Grayswan](../../docs/proxy/guardrails/grayswan)**
|
||||
- Implement fail-open option (default: True) - [PR #18266](https://github.com/BerriAI/litellm/pull/18266)
|
||||
|
||||
- **[Pangea](../../docs/proxy/guardrails/pangea)**
|
||||
- Respect `default_on` during initialization - [PR #18912](https://github.com/BerriAI/litellm/pull/18912)
|
||||
|
||||
- **[Panw Prisma AIRS](../../docs/proxy/guardrails/panw_prisma_airs)**
|
||||
- Add custom violation message support - [PR #19272](https://github.com/BerriAI/litellm/pull/19272)
|
||||
|
||||
- **General Guardrails**
|
||||
- Fix SerializationIterator error and pass tools to guardrail - [PR #18932](https://github.com/BerriAI/litellm/pull/18932)
|
||||
- Properly handle custom guardrails parameters - [PR #18978](https://github.com/BerriAI/litellm/pull/18978)
|
||||
- Use clean error messages for blocked requests - [PR #19023](https://github.com/BerriAI/litellm/pull/19023)
|
||||
- Guardrail moderation support with responses API - [PR #18957](https://github.com/BerriAI/litellm/pull/18957)
|
||||
- Fix model-level guardrails not taking effect - [PR #18895](https://github.com/BerriAI/litellm/pull/18895)
|
||||
|
||||
---
|
||||
|
||||
## Spend Tracking, Budgets and Rate Limiting
|
||||
|
||||
- **Cost Calculation Fixes**
|
||||
- Include IMAGE token count in cost calculation for Gemini models - [PR #18876](https://github.com/BerriAI/litellm/pull/18876)
|
||||
- Fix negative text_tokens when using cache with images - [PR #18768](https://github.com/BerriAI/litellm/pull/18768)
|
||||
- Fix image tokens spend logging for `/images/generations` - [PR #19009](https://github.com/BerriAI/litellm/pull/19009)
|
||||
- Fix incorrect `prompt_tokens_details` in Gemini Image Generation - [PR #19070](https://github.com/BerriAI/litellm/pull/19070)
|
||||
- Fix case-insensitive model cost map lookup - [PR #18208](https://github.com/BerriAI/litellm/pull/18208)
|
||||
|
||||
- **Pricing Updates**
|
||||
- Correct pricing for `openrouter/openai/gpt-oss-20b` - [PR #18899](https://github.com/BerriAI/litellm/pull/18899)
|
||||
- Add pricing for `azure_ai/claude-opus-4-5` - [PR #19003](https://github.com/BerriAI/litellm/pull/19003)
|
||||
- Update Novita models prices - [PR #19005](https://github.com/BerriAI/litellm/pull/19005)
|
||||
- Fix Azure Grok prices - [PR #19102](https://github.com/BerriAI/litellm/pull/19102)
|
||||
- Fix GCP GLM-4.7 pricing - [PR #19172](https://github.com/BerriAI/litellm/pull/19172)
|
||||
- Sync DeepSeek chat/reasoner to V3.2 pricing - [PR #18884](https://github.com/BerriAI/litellm/pull/18884)
|
||||
- Correct cache_read pricing for gemini-2.5-pro models - [PR #18157](https://github.com/BerriAI/litellm/pull/18157)
|
||||
|
||||
- **Budget & Rate Limiting**
|
||||
- Correct budget limit validation operator (>=) for team members - [PR #19207](https://github.com/BerriAI/litellm/pull/19207)
|
||||
- Fix TPM 25% limiting by ensuring priority queue logic - [PR #19092](https://github.com/BerriAI/litellm/pull/19092)
|
||||
- Cleanup spend logs cron verification, fix, and docs - [PR #19085](https://github.com/BerriAI/litellm/pull/19085)
|
||||
|
||||
---
|
||||
|
||||
## MCP Gateway
|
||||
|
||||
- Prevent duplicate MCP reload scheduler registration - [PR #18934](https://github.com/BerriAI/litellm/pull/18934)
|
||||
- Forward MCP extra headers case-insensitively - [PR #18940](https://github.com/BerriAI/litellm/pull/18940)
|
||||
- Fix MCP REST auth checks - [PR #19051](https://github.com/BerriAI/litellm/pull/19051)
|
||||
- Fix generating two telemetry events in responses - [PR #18938](https://github.com/BerriAI/litellm/pull/18938)
|
||||
- Fix MCP chat completions - [PR #19129](https://github.com/BerriAI/litellm/pull/19129)
|
||||
|
||||
---
|
||||
|
||||
## Performance / Loadbalancing / Reliability improvements
|
||||
|
||||
- **Performance Improvements**
|
||||
- Remove bottleneck causing high CPU usage & overhead under heavy load - [PR #19049](https://github.com/BerriAI/litellm/pull/19049)
|
||||
- Add CI enforcement for O(1) operations in `_get_model_cost_key` to prevent performance regressions - [PR #19052](https://github.com/BerriAI/litellm/pull/19052)
|
||||
- Fix Azure embeddings JSON parsing to prevent connection leaks and ensure proper router cooldown - [PR #19167](https://github.com/BerriAI/litellm/pull/19167)
|
||||
- Do not fallback to token counter if `disable_token_counter` is enabled - [PR #19041](https://github.com/BerriAI/litellm/pull/19041)
|
||||
|
||||
- **Reliability**
|
||||
- Add fallback endpoints support - [PR #19185](https://github.com/BerriAI/litellm/pull/19185)
|
||||
- Fix stream_timeout parameter functionality - [PR #19191](https://github.com/BerriAI/litellm/pull/19191)
|
||||
- Fix model matching priority in configuration - [PR #19012](https://github.com/BerriAI/litellm/pull/19012)
|
||||
- Fix num_retries in litellm_params as per config - [PR #18975](https://github.com/BerriAI/litellm/pull/18975)
|
||||
- Handle exceptions without response parameter - [PR #18919](https://github.com/BerriAI/litellm/pull/18919)
|
||||
|
||||
- **Infrastructure**
|
||||
- Add Custom CA certificates to boto3 clients - [PR #18942](https://github.com/BerriAI/litellm/pull/18942)
|
||||
- Update boto3 to 1.40.15 and aioboto3 to 15.5.0 - [PR #19090](https://github.com/BerriAI/litellm/pull/19090)
|
||||
- Make keepalive_timeout parameter work for Gunicorn - [PR #19087](https://github.com/BerriAI/litellm/pull/19087)
|
||||
|
||||
- **Helm Chart**
|
||||
- Fix mount config.yaml as single file in Helm chart - [PR #19146](https://github.com/BerriAI/litellm/pull/19146)
|
||||
- Sync Helm chart versioning with production standards and Docker versions - [PR #18868](https://github.com/BerriAI/litellm/pull/18868)
|
||||
|
||||
---
|
||||
|
||||
## Database Changes
|
||||
|
||||
### Schema Updates
|
||||
|
||||
| Table | Change Type | Description | PR |
|
||||
| ----- | ----------- | ----------- | -- |
|
||||
| `LiteLLM_ProxyModelTable` | New Columns | Added `created_at` and `updated_at` timestamp fields | [PR #18937](https://github.com/BerriAI/litellm/pull/18937) |
|
||||
|
||||
---
|
||||
|
||||
## Documentation Updates
|
||||
|
||||
- Add LiteLLM architecture md doc - [PR #19057](https://github.com/BerriAI/litellm/pull/19057), [PR #19252](https://github.com/BerriAI/litellm/pull/19252)
|
||||
- Add troubleshooting guide - [PR #19096](https://github.com/BerriAI/litellm/pull/19096), [PR #19097](https://github.com/BerriAI/litellm/pull/19097), [PR #19099](https://github.com/BerriAI/litellm/pull/19099)
|
||||
- Add structured issue reporting guides for CPU and memory issues - [PR #19117](https://github.com/BerriAI/litellm/pull/19117)
|
||||
- Add Redis requirement warning for high-traffic deployments - [PR #18892](https://github.com/BerriAI/litellm/pull/18892)
|
||||
- Update load balancing and routing with enable_pre_call_checks - [PR #18888](https://github.com/BerriAI/litellm/pull/18888)
|
||||
- Updated pass_through with guided param - [PR #18886](https://github.com/BerriAI/litellm/pull/18886)
|
||||
- Update message content types link and add content types table - [PR #18209](https://github.com/BerriAI/litellm/pull/18209)
|
||||
- Add Redis initialization with kwargs - [PR #19183](https://github.com/BerriAI/litellm/pull/19183)
|
||||
- Improve documentation for routing LLM calls via SAP Gen AI Hub - [PR #19166](https://github.com/BerriAI/litellm/pull/19166)
|
||||
- Deleted Keys and Teams docs - [PR #19291](https://github.com/BerriAI/litellm/pull/19291)
|
||||
- Claude Code end user tracking guide - [PR #19176](https://github.com/BerriAI/litellm/pull/19176)
|
||||
- Add MCP troubleshooting guide - [PR #19122](https://github.com/BerriAI/litellm/pull/19122)
|
||||
- Add auth message UI documentation - [PR #19063](https://github.com/BerriAI/litellm/pull/19063)
|
||||
- Add guide for mounting custom callbacks in Helm/K8s - [PR #19136](https://github.com/BerriAI/litellm/pull/19136)
|
||||
|
||||
---
|
||||
|
||||
## Bug Fixes
|
||||
|
||||
- Fix Swagger UI path execute error with server_root_path in OpenAPI schema - [PR #18947](https://github.com/BerriAI/litellm/pull/18947)
|
||||
- Normalize OpenAI SDK BaseModel choices/messages to avoid Pydantic serializer warnings - [PR #18972](https://github.com/BerriAI/litellm/pull/18972)
|
||||
- Add contextual gap checks and word-form digits - [PR #18301](https://github.com/BerriAI/litellm/pull/18301)
|
||||
- Clean up orphaned files from repository root - [PR #19150](https://github.com/BerriAI/litellm/pull/19150)
|
||||
- Include proxy/prisma_migration.py in non-root - [PR #18971](https://github.com/BerriAI/litellm/pull/18971)
|
||||
- Update prisma_migration.py - [PR #19083](https://github.com/BerriAI/litellm/pull/19083)
|
||||
|
||||
---
|
||||
|
||||
## New Contributors
|
||||
|
||||
* @yogeshwaran10 made their first contribution in [PR #18898](https://github.com/BerriAI/litellm/pull/18898)
|
||||
* @theonlypal made their first contribution in [PR #18937](https://github.com/BerriAI/litellm/pull/18937)
|
||||
* @jonmagic made their first contribution in [PR #18935](https://github.com/BerriAI/litellm/pull/18935)
|
||||
* @houdataali made their first contribution in [PR #19025](https://github.com/BerriAI/litellm/pull/19025)
|
||||
* @hummat made their first contribution in [PR #18972](https://github.com/BerriAI/litellm/pull/18972)
|
||||
* @berkeyalciin made their first contribution in [PR #18966](https://github.com/BerriAI/litellm/pull/18966)
|
||||
* @MateuszOssGit made their first contribution in [PR #18959](https://github.com/BerriAI/litellm/pull/18959)
|
||||
* @xfan001 made their first contribution in [PR #18947](https://github.com/BerriAI/litellm/pull/18947)
|
||||
* @nulone made their first contribution in [PR #18884](https://github.com/BerriAI/litellm/pull/18884)
|
||||
* @debnil-mercor made their first contribution in [PR #18919](https://github.com/BerriAI/litellm/pull/18919)
|
||||
* @hakhundov made their first contribution in [PR #17420](https://github.com/BerriAI/litellm/pull/17420)
|
||||
* @rohanwinsor made their first contribution in [PR #19078](https://github.com/BerriAI/litellm/pull/19078)
|
||||
* @pgolm made their first contribution in [PR #19020](https://github.com/BerriAI/litellm/pull/19020)
|
||||
* @vikigenius made their first contribution in [PR #19148](https://github.com/BerriAI/litellm/pull/19148)
|
||||
* @burnerburnerburnerman made their first contribution in [PR #19090](https://github.com/BerriAI/litellm/pull/19090)
|
||||
* @yfge made their first contribution in [PR #19076](https://github.com/BerriAI/litellm/pull/19076)
|
||||
* @danielnyari-seon made their first contribution in [PR #19083](https://github.com/BerriAI/litellm/pull/19083)
|
||||
* @guilherme-segantini made their first contribution in [PR #19166](https://github.com/BerriAI/litellm/pull/19166)
|
||||
* @jgreek made their first contribution in [PR #19147](https://github.com/BerriAI/litellm/pull/19147)
|
||||
* @anand-kamble made their first contribution in [PR #19193](https://github.com/BerriAI/litellm/pull/19193)
|
||||
* @neubig made their first contribution in [PR #19162](https://github.com/BerriAI/litellm/pull/19162)
|
||||
|
||||
---
|
||||
|
||||
## Full Changelog
|
||||
|
||||
**[View complete changelog on GitHub](https://github.com/BerriAI/litellm/compare/v1.80.15.rc.1...v1.81.0.rc.1)**
|
||||
|
|
@ -122,6 +122,7 @@ const sidebars = {
|
|||
items: [
|
||||
"tutorials/claude_responses_api",
|
||||
"tutorials/claude_code_customer_tracking",
|
||||
"tutorials/claude_code_websearch",
|
||||
"tutorials/claude_mcp",
|
||||
"tutorials/claude_non_anthropic_models",
|
||||
]
|
||||
|
|
@ -274,12 +275,21 @@ const sidebars = {
|
|||
"proxy/ui/bulk_edit_users",
|
||||
"proxy/ui_credentials",
|
||||
"tutorials/scim_litellm",
|
||||
{
|
||||
type: "category",
|
||||
label: "UI Usage Tracking",
|
||||
items: [
|
||||
"proxy/customer_usage",
|
||||
"proxy/endpoint_activity"
|
||||
]
|
||||
},
|
||||
{
|
||||
type: "category",
|
||||
label: "UI Logs",
|
||||
items: [
|
||||
"proxy/ui_logs",
|
||||
"proxy/ui_logs_sessions"
|
||||
"proxy/ui_logs_sessions",
|
||||
"proxy/deleted_keys_teams"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
|
@ -329,7 +339,6 @@ const sidebars = {
|
|||
"proxy/team_budgets",
|
||||
"proxy/tag_budgets",
|
||||
"proxy/customers",
|
||||
"proxy/customer_usage",
|
||||
"proxy/dynamic_rate_limit",
|
||||
"proxy/rate_limit_tiers",
|
||||
"proxy/temporary_budget_increase",
|
||||
|
|
|
|||
|
|
@ -1,2 +0,0 @@
|
|||
-- This is an empty migration.
|
||||
|
||||
|
|
@ -1,2 +0,0 @@
|
|||
-- This is an empty migration.
|
||||
|
||||
|
|
@ -113,7 +113,9 @@ def _get_a2a_model_info(a2a_client: Any, kwargs: Dict[str, Any]) -> str:
|
|||
litellm_logging_obj.model = model
|
||||
litellm_logging_obj.custom_llm_provider = custom_llm_provider
|
||||
litellm_logging_obj.model_call_details["model"] = model
|
||||
litellm_logging_obj.model_call_details["custom_llm_provider"] = custom_llm_provider
|
||||
litellm_logging_obj.model_call_details[
|
||||
"custom_llm_provider"
|
||||
] = custom_llm_provider
|
||||
|
||||
return agent_name
|
||||
|
||||
|
|
@ -197,7 +199,11 @@ async def asend_message(
|
|||
)
|
||||
|
||||
# Extract params from request
|
||||
params = request.params.model_dump(mode="json") if hasattr(request.params, "model_dump") else dict(request.params)
|
||||
params = (
|
||||
request.params.model_dump(mode="json")
|
||||
if hasattr(request.params, "model_dump")
|
||||
else dict(request.params)
|
||||
)
|
||||
|
||||
response_dict = await A2ACompletionBridgeHandler.handle_non_streaming(
|
||||
request_id=str(request.id),
|
||||
|
|
@ -216,7 +222,9 @@ async def asend_message(
|
|||
# Create A2A client if not provided but api_base is available
|
||||
if a2a_client is None:
|
||||
if api_base is None:
|
||||
raise ValueError("Either a2a_client or api_base is required for standard A2A flow")
|
||||
raise ValueError(
|
||||
"Either a2a_client or api_base is required for standard A2A flow"
|
||||
)
|
||||
a2a_client = await create_a2a_client(base_url=api_base)
|
||||
|
||||
# Type assertion: a2a_client is guaranteed to be non-None here
|
||||
|
|
@ -235,7 +243,11 @@ async def asend_message(
|
|||
|
||||
# Calculate token usage from request and response
|
||||
response_dict = a2a_response.model_dump(mode="json", exclude_none=True)
|
||||
prompt_tokens, completion_tokens, _ = A2ARequestUtils.calculate_usage_from_request_response(
|
||||
(
|
||||
prompt_tokens,
|
||||
completion_tokens,
|
||||
_,
|
||||
) = A2ARequestUtils.calculate_usage_from_request_response(
|
||||
request=request,
|
||||
response_dict=response_dict,
|
||||
)
|
||||
|
|
@ -280,7 +292,9 @@ def send_message(
|
|||
if loop is not None:
|
||||
return asend_message(a2a_client=a2a_client, request=request, **kwargs)
|
||||
else:
|
||||
return asyncio.run(asend_message(a2a_client=a2a_client, request=request, **kwargs))
|
||||
return asyncio.run(
|
||||
asend_message(a2a_client=a2a_client, request=request, **kwargs)
|
||||
)
|
||||
|
||||
|
||||
async def asend_message_streaming(
|
||||
|
|
@ -347,7 +361,11 @@ async def asend_message_streaming(
|
|||
)
|
||||
|
||||
# Extract params from request
|
||||
params = request.params.model_dump(mode="json") if hasattr(request.params, "model_dump") else dict(request.params)
|
||||
params = (
|
||||
request.params.model_dump(mode="json")
|
||||
if hasattr(request.params, "model_dump")
|
||||
else dict(request.params)
|
||||
)
|
||||
|
||||
async for chunk in A2ACompletionBridgeHandler.handle_streaming(
|
||||
request_id=str(request.id),
|
||||
|
|
@ -365,7 +383,9 @@ async def asend_message_streaming(
|
|||
# Create A2A client if not provided but api_base is available
|
||||
if a2a_client is None:
|
||||
if api_base is None:
|
||||
raise ValueError("Either a2a_client or api_base is required for standard A2A flow")
|
||||
raise ValueError(
|
||||
"Either a2a_client or api_base is required for standard A2A flow"
|
||||
)
|
||||
a2a_client = await create_a2a_client(base_url=api_base)
|
||||
|
||||
# Type assertion: a2a_client is guaranteed to be non-None here
|
||||
|
|
@ -378,7 +398,9 @@ async def asend_message_streaming(
|
|||
stream = a2a_client.send_message_streaming(request)
|
||||
|
||||
# Build logging object for streaming completion callbacks
|
||||
agent_card = getattr(a2a_client, "_litellm_agent_card", None) or getattr(a2a_client, "agent_card", None)
|
||||
agent_card = getattr(a2a_client, "_litellm_agent_card", None) or getattr(
|
||||
a2a_client, "agent_card", None
|
||||
)
|
||||
agent_name = getattr(agent_card, "name", "unknown") if agent_card else "unknown"
|
||||
model = f"a2a_agent/{agent_name}"
|
||||
|
||||
|
|
@ -456,7 +478,7 @@ async def create_a2a_client(
|
|||
if not A2A_SDK_AVAILABLE:
|
||||
raise ImportError(
|
||||
"The 'a2a' package is required for A2A agent invocation. "
|
||||
"Install it with: pip install a2a"
|
||||
"Install it with: pip install a2a-sdk"
|
||||
)
|
||||
|
||||
verbose_logger.info(f"Creating A2A client for {base_url}")
|
||||
|
|
@ -512,7 +534,7 @@ async def aget_agent_card(
|
|||
if not A2A_SDK_AVAILABLE:
|
||||
raise ImportError(
|
||||
"The 'a2a' package is required for A2A agent invocation. "
|
||||
"Install it with: pip install a2a"
|
||||
"Install it with: pip install a2a-sdk"
|
||||
)
|
||||
|
||||
verbose_logger.info(f"Fetching agent card from {base_url}")
|
||||
|
|
@ -534,5 +556,3 @@ async def aget_agent_card(
|
|||
f"Fetched agent card: {agent_card.name if hasattr(agent_card, 'name') else 'unknown'}"
|
||||
)
|
||||
return agent_card
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -329,6 +329,11 @@ ANTHROPIC_WEB_SEARCH_TOOL_MAX_USES = {
|
|||
"medium": 5,
|
||||
"high": 10,
|
||||
}
|
||||
|
||||
# LiteLLM standard web search tool name
|
||||
# Used for web search interception across providers
|
||||
LITELLM_WEB_SEARCH_TOOL_NAME = "litellm_web_search"
|
||||
|
||||
DEFAULT_IMAGE_ENDPOINT_MODEL = "dall-e-2"
|
||||
DEFAULT_VIDEO_ENDPOINT_MODEL = "sora-2"
|
||||
|
||||
|
|
|
|||
|
|
@ -714,8 +714,8 @@ def image_variation(
|
|||
|
||||
@client
|
||||
def image_edit( # noqa: PLR0915
|
||||
image: Union[FileTypes, List[FileTypes]],
|
||||
prompt: str,
|
||||
image: Optional[Union[FileTypes, List[FileTypes]]] = None,
|
||||
prompt: Optional[str]= None,
|
||||
model: Optional[str] = None,
|
||||
mask: Optional[str] = None,
|
||||
n: Optional[int] = None,
|
||||
|
|
@ -766,7 +766,7 @@ def image_edit( # noqa: PLR0915
|
|||
_is_async = kwargs.pop("async_call", False) is True
|
||||
|
||||
# add images / or return a single image
|
||||
images = image if isinstance(image, list) else [image]
|
||||
images = image if isinstance(image, list) else ([image] if image is not None else [])
|
||||
|
||||
headers_from_kwargs = kwargs.get("headers")
|
||||
merged_extra_headers: Dict[str, Any] = {}
|
||||
|
|
|
|||
|
|
@ -143,6 +143,34 @@ class CustomLogger: # https://docs.litellm.ai/docs/observability/custom_callbac
|
|||
async def async_log_pre_api_call(self, model, messages, kwargs):
|
||||
pass
|
||||
|
||||
async def async_pre_request_hook(
|
||||
self, model: str, messages: List, kwargs: Dict
|
||||
) -> Optional[Dict]:
|
||||
"""
|
||||
Hook called before making the API request to allow modifying request parameters.
|
||||
|
||||
This is specifically designed for modifying the request before it's sent to the provider.
|
||||
Unlike async_log_pre_api_call (which is for logging), this hook is meant for transformations.
|
||||
|
||||
Args:
|
||||
model: The model name
|
||||
messages: The messages list
|
||||
kwargs: The request parameters (tools, stream, temperature, etc.)
|
||||
|
||||
Returns:
|
||||
Optional[Dict]: Modified kwargs to use for the request, or None if no modifications
|
||||
|
||||
Example:
|
||||
```python
|
||||
async def async_pre_request_hook(self, model, messages, kwargs):
|
||||
# Convert native tools to standard format
|
||||
if kwargs.get("tools"):
|
||||
kwargs["tools"] = convert_tools(kwargs["tools"])
|
||||
return kwargs
|
||||
```
|
||||
"""
|
||||
pass
|
||||
|
||||
async def async_log_success_event(self, kwargs, response_obj, start_time, end_time):
|
||||
pass
|
||||
|
||||
|
|
|
|||
|
|
@ -987,7 +987,10 @@ class OpenTelemetry(CustomLogger):
|
|||
# TODO: Refactor to use the proper OTEL Logs API instead of directly creating SDK LogRecords
|
||||
|
||||
from opentelemetry._logs import SeverityNumber, get_logger, get_logger_provider
|
||||
from opentelemetry.sdk._logs import LogRecord as SdkLogRecord
|
||||
try:
|
||||
from opentelemetry.sdk._logs import LogRecord as SdkLogRecord # OTEL < 1.39.0
|
||||
except ImportError:
|
||||
from opentelemetry.sdk._logs._internal import LogRecord as SdkLogRecord # OTEL >= 1.39.0
|
||||
|
||||
otel_logger = get_logger(LITELLM_LOGGER_NAME)
|
||||
|
||||
|
|
|
|||
|
|
@ -21,7 +21,12 @@ from typing import (
|
|||
import litellm
|
||||
from litellm._logging import print_verbose, verbose_logger
|
||||
from litellm.integrations.custom_logger import CustomLogger
|
||||
from litellm.proxy._types import LiteLLM_TeamTable, LiteLLM_UserTable, UserAPIKeyAuth
|
||||
from litellm.proxy._types import (
|
||||
LiteLLM_DeletedVerificationToken,
|
||||
LiteLLM_TeamTable,
|
||||
LiteLLM_UserTable,
|
||||
UserAPIKeyAuth,
|
||||
)
|
||||
from litellm.types.integrations.prometheus import *
|
||||
from litellm.types.integrations.prometheus import _sanitize_prometheus_label_name
|
||||
from litellm.types.utils import StandardLoggingPayload
|
||||
|
|
@ -2153,7 +2158,7 @@ class PrometheusLogger(CustomLogger):
|
|||
self,
|
||||
data_fetch_function: Callable[..., Awaitable[Tuple[List[Any], Optional[int]]]],
|
||||
set_metrics_function: Callable[[List[Any]], Awaitable[None]],
|
||||
data_type: Literal["teams", "keys"],
|
||||
data_type: Literal["teams", "keys", "users"],
|
||||
):
|
||||
"""
|
||||
Generic method to initialize budget metrics for teams or API keys.
|
||||
|
|
@ -2245,7 +2250,7 @@ class PrometheusLogger(CustomLogger):
|
|||
|
||||
async def fetch_keys(
|
||||
page_size: int, page: int
|
||||
) -> Tuple[List[Union[str, UserAPIKeyAuth]], Optional[int]]:
|
||||
) -> Tuple[List[Union[str, UserAPIKeyAuth, LiteLLM_DeletedVerificationToken]], Optional[int]]:
|
||||
key_list_response = await _list_key_helper(
|
||||
prisma_client=prisma_client,
|
||||
page=page,
|
||||
|
|
|
|||
|
|
@ -7,6 +7,98 @@ Server-side WebSearch tool execution for models that don't natively support it (
|
|||
User makes **ONE** `litellm.messages.acreate()` call → Gets final answer with search results.
|
||||
The agentic loop happens transparently on the server.
|
||||
|
||||
## LiteLLM Standard Web Search Tool
|
||||
|
||||
LiteLLM defines a standard web search tool format (`litellm_web_search`) that all native provider tools are converted to. This enables consistent interception across providers.
|
||||
|
||||
**Standard Tool Definition** (defined in `tools.py`):
|
||||
```python
|
||||
{
|
||||
"name": "litellm_web_search",
|
||||
"description": "Search the web for information...",
|
||||
"input_schema": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"query": {"type": "string", "description": "The search query"}
|
||||
},
|
||||
"required": ["query"]
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Tool Name Constant**: `LITELLM_WEB_SEARCH_TOOL_NAME = "litellm_web_search"` (defined in `litellm/constants.py`)
|
||||
|
||||
### Supported Tool Formats
|
||||
|
||||
The interception system automatically detects and handles:
|
||||
|
||||
| Tool Format | Example | Provider | Detection Method | Future-Proof |
|
||||
|-------------|---------|----------|------------------|-------------|
|
||||
| **LiteLLM Standard** | `name="litellm_web_search"` | Any | Direct name match | N/A |
|
||||
| **Anthropic Native** | `type="web_search_20250305"` | Bedrock, Claude API | Type prefix: `startswith("web_search_")` | ✅ Yes (web_search_2026, etc.) |
|
||||
| **Claude Code CLI** | `name="web_search"`, `type="web_search_20250305"` | Claude Code | Name + type check | ✅ Yes (version-agnostic) |
|
||||
| **Legacy** | `name="WebSearch"` | Custom | Name match | N/A (backwards compat) |
|
||||
|
||||
**Future Compatibility**: The `startswith("web_search_")` check in `tools.py` automatically supports future Anthropic web search versions.
|
||||
|
||||
### Claude Code CLI Integration
|
||||
|
||||
Claude Code (Anthropic's official CLI) sends web search requests using Anthropic's native tool format:
|
||||
|
||||
```python
|
||||
{
|
||||
"type": "web_search_20250305",
|
||||
"name": "web_search",
|
||||
"max_uses": 8
|
||||
}
|
||||
```
|
||||
|
||||
**What Happens:**
|
||||
1. Claude Code sends native `web_search_20250305` tool to LiteLLM proxy
|
||||
2. LiteLLM intercepts and converts to `litellm_web_search` standard format
|
||||
3. Bedrock receives converted tool (NOT native format)
|
||||
4. Model returns `tool_use` block for `litellm_web_search` (not `server_tool_use`)
|
||||
5. LiteLLM's agentic loop intercepts the `tool_use`
|
||||
6. Executes `litellm.asearch()` using configured provider (Perplexity, Tavily, etc.)
|
||||
7. Returns final answer to Claude Code user
|
||||
|
||||
**Without Interception**: Bedrock would receive native tool → try to execute natively → return `web_search_tool_result_error` with `invalid_tool_input`
|
||||
|
||||
**With Interception**: LiteLLM converts → Bedrock returns tool_use → LiteLLM executes search → Returns final answer ✅
|
||||
|
||||
### Native Tool Conversion
|
||||
|
||||
Native tools are converted to LiteLLM standard format **before** sending to the provider:
|
||||
|
||||
1. **Conversion Point** (`litellm/llms/anthropic/experimental_pass_through/messages/handler.py`):
|
||||
- In `anthropic_messages()` function (lines 60-127)
|
||||
- Runs BEFORE the API request is made
|
||||
- Detects native web search tools using `is_web_search_tool()`
|
||||
- Converts to `litellm_web_search` format using `get_litellm_web_search_tool()`
|
||||
- Prevents provider from executing search natively (avoids `web_search_tool_result_error`)
|
||||
|
||||
2. **Response Detection** (`transformation.py`):
|
||||
- Detects `tool_use` blocks with any web search tool name
|
||||
- Handles: `litellm_web_search`, `WebSearch`, `web_search`
|
||||
- Extracts search queries for execution
|
||||
|
||||
**Example Conversion**:
|
||||
```python
|
||||
# Input (Claude Code's native tool)
|
||||
{
|
||||
"type": "web_search_20250305",
|
||||
"name": "web_search",
|
||||
"max_uses": 8
|
||||
}
|
||||
|
||||
# Output (LiteLLM standard)
|
||||
{
|
||||
"name": "litellm_web_search",
|
||||
"description": "Search the web for information...",
|
||||
"input_schema": {...}
|
||||
}
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Request Flow
|
||||
|
|
@ -63,6 +155,9 @@ sequenceDiagram
|
|||
| Component | File | Purpose |
|
||||
|-----------|------|---------|
|
||||
| **WebSearchInterceptionLogger** | `handler.py` | CustomLogger that implements agentic loop hooks |
|
||||
| **Tool Standardization** | `tools.py` | Standard tool definition, detection, and utilities |
|
||||
| **Tool Name Constant** | `constants.py` | `LITELLM_WEB_SEARCH_TOOL_NAME = "litellm_web_search"` |
|
||||
| **Tool Conversion** | `anthropic/.../ handler.py` | Converts native tools to LiteLLM standard before API call |
|
||||
| **Transformation Logic** | `transformation.py` | Detect tool_use, build tool_result messages, format search responses |
|
||||
| **Agentic Loop Hooks** | `integrations/custom_logger.py` | Base hooks: `async_should_run_agentic_loop()`, `async_run_agentic_loop()` |
|
||||
| **Hook Orchestration** | `llms/custom_httpx/llm_http_handler.py` | `_call_agentic_completion_hooks()` - calls hooks after response |
|
||||
|
|
@ -74,7 +169,10 @@ sequenceDiagram
|
|||
## Configuration
|
||||
|
||||
```python
|
||||
from litellm.integrations.websearch_interception import WebSearchInterceptionLogger
|
||||
from litellm.integrations.websearch_interception import (
|
||||
WebSearchInterceptionLogger,
|
||||
get_litellm_web_search_tool,
|
||||
)
|
||||
from litellm.types.utils import LlmProviders
|
||||
|
||||
# Enable for Bedrock with specific search tool
|
||||
|
|
@ -85,13 +183,25 @@ litellm.callbacks = [
|
|||
)
|
||||
]
|
||||
|
||||
# Make request (streaming or non-streaming both work)
|
||||
# Make request with LiteLLM standard tool (recommended)
|
||||
response = await litellm.messages.acreate(
|
||||
model="bedrock/us.anthropic.claude-3-5-sonnet-20241022-v2:0",
|
||||
model="bedrock/us.anthropic.claude-sonnet-4-5-20250929-v1:0",
|
||||
messages=[{"role": "user", "content": "What is LiteLLM?"}],
|
||||
tools=[{"name": "WebSearch", ...}],
|
||||
tools=[get_litellm_web_search_tool()], # LiteLLM standard
|
||||
max_tokens=1024,
|
||||
stream=True # Auto-converted to non-streaming
|
||||
)
|
||||
|
||||
# OR send native tools - they're auto-converted to LiteLLM standard
|
||||
response = await litellm.messages.acreate(
|
||||
model="bedrock/us.anthropic.claude-sonnet-4-5-20250929-v1:0",
|
||||
messages=[{"role": "user", "content": "What is LiteLLM?"}],
|
||||
tools=[{
|
||||
"type": "web_search_20250305", # Native Anthropic format
|
||||
"name": "web_search",
|
||||
"max_uses": 8
|
||||
}],
|
||||
max_tokens=1024,
|
||||
stream=True # Streaming is automatically converted to non-streaming for WebSearch
|
||||
)
|
||||
```
|
||||
|
||||
|
|
|
|||
|
|
@ -8,5 +8,13 @@ support server-side tool calling (e.g., Bedrock/Claude).
|
|||
from litellm.integrations.websearch_interception.handler import (
|
||||
WebSearchInterceptionLogger,
|
||||
)
|
||||
from litellm.integrations.websearch_interception.tools import (
|
||||
get_litellm_web_search_tool,
|
||||
is_web_search_tool,
|
||||
)
|
||||
|
||||
__all__ = ["WebSearchInterceptionLogger"]
|
||||
__all__ = [
|
||||
"WebSearchInterceptionLogger",
|
||||
"get_litellm_web_search_tool",
|
||||
"is_web_search_tool",
|
||||
]
|
||||
|
|
|
|||
|
|
@ -12,7 +12,12 @@ from typing import Any, Dict, List, Optional, Tuple, Union, cast
|
|||
import litellm
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.anthropic_interface import messages as anthropic_messages
|
||||
from litellm.constants import LITELLM_WEB_SEARCH_TOOL_NAME
|
||||
from litellm.integrations.custom_logger import CustomLogger
|
||||
from litellm.integrations.websearch_interception.tools import (
|
||||
get_litellm_web_search_tool,
|
||||
is_web_search_tool,
|
||||
)
|
||||
from litellm.integrations.websearch_interception.transformation import (
|
||||
WebSearchTransformation,
|
||||
)
|
||||
|
|
@ -57,6 +62,55 @@ class WebSearchInterceptionLogger(CustomLogger):
|
|||
for p in enabled_providers
|
||||
]
|
||||
self.search_tool_name = search_tool_name
|
||||
self._request_has_websearch = False # Track if current request has web search
|
||||
|
||||
async def async_pre_call_deployment_hook(
|
||||
self, kwargs: Dict[str, Any], call_type: Optional[Any]
|
||||
) -> Optional[dict]:
|
||||
"""
|
||||
Pre-call hook to convert native Anthropic web_search tools to regular tools.
|
||||
|
||||
This prevents Bedrock from trying to execute web search server-side (which fails).
|
||||
Instead, we convert it to a regular tool so the model returns tool_use blocks
|
||||
that we can intercept and execute ourselves.
|
||||
"""
|
||||
# Check if this is for an enabled provider
|
||||
custom_llm_provider = kwargs.get("litellm_params", {}).get("custom_llm_provider", "")
|
||||
if custom_llm_provider not in self.enabled_providers:
|
||||
return None
|
||||
|
||||
# Check if request has tools with native web_search
|
||||
tools = kwargs.get("tools")
|
||||
if not tools:
|
||||
return None
|
||||
|
||||
# Check if any tool is a web search tool (native or already LiteLLM standard)
|
||||
has_websearch = any(is_web_search_tool(t) for t in tools)
|
||||
|
||||
if not has_websearch:
|
||||
return None
|
||||
|
||||
verbose_logger.debug(
|
||||
"WebSearchInterception: Converting native web_search tools to LiteLLM standard"
|
||||
)
|
||||
|
||||
# Convert native/custom web_search tools to LiteLLM standard
|
||||
converted_tools = []
|
||||
for tool in tools:
|
||||
if is_web_search_tool(tool):
|
||||
# Convert to LiteLLM standard web search tool
|
||||
converted_tool = get_litellm_web_search_tool()
|
||||
converted_tools.append(converted_tool)
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Converted {tool.get('name', 'unknown')} "
|
||||
f"(type={tool.get('type', 'none')}) to {LITELLM_WEB_SEARCH_TOOL_NAME}"
|
||||
)
|
||||
else:
|
||||
# Keep other tools as-is
|
||||
converted_tools.append(tool)
|
||||
|
||||
# Return modified kwargs with converted tools
|
||||
return {"tools": converted_tools}
|
||||
|
||||
@classmethod
|
||||
def from_config_yaml(
|
||||
|
|
@ -104,6 +158,83 @@ class WebSearchInterceptionLogger(CustomLogger):
|
|||
search_tool_name=search_tool_name,
|
||||
)
|
||||
|
||||
async def async_pre_request_hook(
|
||||
self, model: str, messages: List[Dict], kwargs: Dict
|
||||
) -> Optional[Dict]:
|
||||
"""
|
||||
Pre-request hook to convert native web search tools to LiteLLM standard.
|
||||
|
||||
This hook is called before the API request is made, allowing us to:
|
||||
1. Detect native web search tools (web_search_20250305, etc.)
|
||||
2. Convert them to LiteLLM standard format (litellm_web_search)
|
||||
3. Convert stream=True to stream=False for interception
|
||||
|
||||
This prevents providers like Bedrock from trying to execute web search
|
||||
natively (which fails), and ensures our agentic loop can intercept tool_use.
|
||||
|
||||
Returns:
|
||||
Modified kwargs dict with converted tools, or None if no modifications needed
|
||||
"""
|
||||
# Check if this request is for an enabled provider
|
||||
custom_llm_provider = kwargs.get("litellm_params", {}).get(
|
||||
"custom_llm_provider", ""
|
||||
)
|
||||
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Pre-request hook called"
|
||||
f" - custom_llm_provider={custom_llm_provider}"
|
||||
f" - enabled_providers={self.enabled_providers}"
|
||||
)
|
||||
|
||||
if custom_llm_provider not in self.enabled_providers:
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Skipping - provider {custom_llm_provider} not in {self.enabled_providers}"
|
||||
)
|
||||
return None
|
||||
|
||||
# Check if request has tools
|
||||
tools = kwargs.get("tools")
|
||||
if not tools:
|
||||
return None
|
||||
|
||||
# Check if any tool is a web search tool
|
||||
has_websearch = any(is_web_search_tool(t) for t in tools)
|
||||
if not has_websearch:
|
||||
return None
|
||||
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Pre-request hook triggered for provider={custom_llm_provider}"
|
||||
)
|
||||
|
||||
# Convert native web search tools to LiteLLM standard
|
||||
converted_tools = []
|
||||
for tool in tools:
|
||||
if is_web_search_tool(tool):
|
||||
standard_tool = get_litellm_web_search_tool()
|
||||
converted_tools.append(standard_tool)
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Converted {tool.get('name', 'unknown')} "
|
||||
f"(type={tool.get('type', 'none')}) to {LITELLM_WEB_SEARCH_TOOL_NAME}"
|
||||
)
|
||||
else:
|
||||
converted_tools.append(tool)
|
||||
|
||||
# Update kwargs with converted tools
|
||||
kwargs["tools"] = converted_tools
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Tools after conversion: {[t.get('name') for t in converted_tools]}"
|
||||
)
|
||||
|
||||
# Convert stream=True to stream=False for WebSearch interception
|
||||
if kwargs.get("stream"):
|
||||
verbose_logger.debug(
|
||||
"WebSearchInterception: Converting stream=True to stream=False"
|
||||
)
|
||||
kwargs["stream"] = False
|
||||
kwargs["_websearch_interception_converted_stream"] = True
|
||||
|
||||
return kwargs
|
||||
|
||||
async def async_should_run_agentic_loop(
|
||||
self,
|
||||
response: Any,
|
||||
|
|
@ -128,11 +259,11 @@ class WebSearchInterceptionLogger(CustomLogger):
|
|||
)
|
||||
return False, {}
|
||||
|
||||
# Check if tools include WebSearch
|
||||
has_websearch_tool = any(t.get("name") == "WebSearch" for t in (tools or []))
|
||||
# Check if tools include any web search tool (LiteLLM standard or native)
|
||||
has_websearch_tool = any(is_web_search_tool(t) for t in (tools or []))
|
||||
if not has_websearch_tool:
|
||||
verbose_logger.debug(
|
||||
"WebSearchInterception: No WebSearch tool in request"
|
||||
"WebSearchInterception: No web search tool in request"
|
||||
)
|
||||
return False, {}
|
||||
|
||||
|
|
|
|||
95
litellm/integrations/websearch_interception/tools.py
Normal file
95
litellm/integrations/websearch_interception/tools.py
Normal file
|
|
@ -0,0 +1,95 @@
|
|||
"""
|
||||
LiteLLM Web Search Tool Definition
|
||||
|
||||
This module defines the standard web search tool used across LiteLLM.
|
||||
Native provider tools (like Anthropic's web_search_20250305) are converted
|
||||
to this format for consistent interception and execution.
|
||||
"""
|
||||
|
||||
from typing import Any, Dict
|
||||
|
||||
from litellm.constants import LITELLM_WEB_SEARCH_TOOL_NAME
|
||||
|
||||
|
||||
def get_litellm_web_search_tool() -> Dict[str, Any]:
|
||||
"""
|
||||
Get the standard LiteLLM web search tool definition.
|
||||
|
||||
This is the canonical tool definition that all native web search tools
|
||||
(like Anthropic's web_search_20250305, Claude Code's web_search, etc.)
|
||||
are converted to for interception.
|
||||
|
||||
Returns:
|
||||
Dict containing the Anthropic-style tool definition with:
|
||||
- name: Tool name
|
||||
- description: What the tool does
|
||||
- input_schema: JSON schema for tool parameters
|
||||
|
||||
Example:
|
||||
>>> tool = get_litellm_web_search_tool()
|
||||
>>> tool['name']
|
||||
'litellm_web_search'
|
||||
"""
|
||||
return {
|
||||
"name": LITELLM_WEB_SEARCH_TOOL_NAME,
|
||||
"description": (
|
||||
"Search the web for information. Use this when you need current "
|
||||
"information or answers to questions that require up-to-date data."
|
||||
),
|
||||
"input_schema": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"query": {
|
||||
"type": "string",
|
||||
"description": "The search query to execute"
|
||||
}
|
||||
},
|
||||
"required": ["query"]
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
def is_web_search_tool(tool: Dict[str, Any]) -> bool:
|
||||
"""
|
||||
Check if a tool is a web search tool (native or LiteLLM standard).
|
||||
|
||||
Detects:
|
||||
- LiteLLM standard: name == "litellm_web_search"
|
||||
- Anthropic native: type starts with "web_search_" (e.g., "web_search_20250305")
|
||||
- Claude Code: name == "web_search" with a type field
|
||||
- Custom: name == "WebSearch" (legacy format)
|
||||
|
||||
Args:
|
||||
tool: Tool dictionary to check
|
||||
|
||||
Returns:
|
||||
True if tool is a web search tool
|
||||
|
||||
Example:
|
||||
>>> is_web_search_tool({"name": "litellm_web_search"})
|
||||
True
|
||||
>>> is_web_search_tool({"type": "web_search_20250305", "name": "web_search"})
|
||||
True
|
||||
>>> is_web_search_tool({"name": "calculator"})
|
||||
False
|
||||
"""
|
||||
tool_name = tool.get("name", "")
|
||||
tool_type = tool.get("type", "")
|
||||
|
||||
# Check for LiteLLM standard tool
|
||||
if tool_name == LITELLM_WEB_SEARCH_TOOL_NAME:
|
||||
return True
|
||||
|
||||
# Check for native Anthropic web_search_* types
|
||||
if tool_type.startswith("web_search_"):
|
||||
return True
|
||||
|
||||
# Check for Claude Code's web_search with a type field
|
||||
if tool_name == "web_search" and tool_type:
|
||||
return True
|
||||
|
||||
# Check for legacy WebSearch format
|
||||
if tool_name == "WebSearch":
|
||||
return True
|
||||
|
||||
return False
|
||||
|
|
@ -7,6 +7,7 @@ Transforms between Anthropic tool_use format and LiteLLM search format.
|
|||
from typing import Any, Dict, List, Tuple
|
||||
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.constants import LITELLM_WEB_SEARCH_TOOL_NAME
|
||||
from litellm.llms.base_llm.search.transformation import SearchResponse
|
||||
|
||||
|
||||
|
|
@ -94,17 +95,21 @@ class WebSearchTransformation:
|
|||
block_id = getattr(block, "id", None)
|
||||
block_input = getattr(block, "input", {})
|
||||
|
||||
if block_type == "tool_use" and block_name == "WebSearch":
|
||||
# Check for LiteLLM standard or legacy web search tools
|
||||
# Handles: litellm_web_search, WebSearch, web_search
|
||||
if block_type == "tool_use" and block_name in (
|
||||
LITELLM_WEB_SEARCH_TOOL_NAME, "WebSearch", "web_search"
|
||||
):
|
||||
# Convert to dict for easier handling
|
||||
tool_call = {
|
||||
"id": block_id,
|
||||
"type": "tool_use",
|
||||
"name": "WebSearch",
|
||||
"name": block_name, # Preserve original name
|
||||
"input": block_input,
|
||||
}
|
||||
tool_calls.append(tool_call)
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Found WebSearch tool_use with id={tool_call['id']}"
|
||||
f"WebSearchInterception: Found {block_name} tool_use with id={tool_call['id']}"
|
||||
)
|
||||
|
||||
return len(tool_calls) > 0, tool_calls
|
||||
|
|
|
|||
|
|
@ -4410,9 +4410,10 @@ def _bedrock_tools_pt(tools: List) -> List[BedrockToolBlock]:
|
|||
|
||||
defs = parameters.pop("$defs", {})
|
||||
defs_copy = copy.deepcopy(defs)
|
||||
# flatten the defs
|
||||
for _, value in defs_copy.items():
|
||||
unpack_defs(value, defs_copy)
|
||||
# Expand $ref references in parameters using the definitions
|
||||
# Note: We don't pre-flatten defs as that causes exponential memory growth
|
||||
# with circular references (see issue #19098). unpack_defs handles nested
|
||||
# refs recursively and correctly detects/skips circular references.
|
||||
unpack_defs(parameters, defs_copy)
|
||||
tool_input_schema = BedrockToolInputSchemaBlock(
|
||||
json=BedrockToolJsonSchemaBlock(
|
||||
|
|
|
|||
|
|
@ -934,8 +934,15 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
)
|
||||
return tools
|
||||
|
||||
def _ensure_context_management_beta_header(self, headers: dict) -> None:
|
||||
beta_value = ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value
|
||||
def _ensure_beta_header(self, headers: dict, beta_value: str) -> None:
|
||||
"""
|
||||
Ensure a beta header value is present in the anthropic-beta header.
|
||||
Merges with existing values instead of overriding them.
|
||||
|
||||
Args:
|
||||
headers: Dictionary of headers to update
|
||||
beta_value: The beta header value to add
|
||||
"""
|
||||
existing_beta = headers.get("anthropic-beta")
|
||||
if existing_beta is None:
|
||||
headers["anthropic-beta"] = beta_value
|
||||
|
|
@ -944,6 +951,10 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
if beta_value not in existing_values:
|
||||
headers["anthropic-beta"] = f"{existing_beta}, {beta_value}"
|
||||
|
||||
def _ensure_context_management_beta_header(self, headers: dict) -> None:
|
||||
beta_value = ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value
|
||||
self._ensure_beta_header(headers, beta_value)
|
||||
|
||||
def update_headers_with_optional_anthropic_beta(
|
||||
self, headers: dict, optional_params: dict
|
||||
) -> dict:
|
||||
|
|
@ -960,20 +971,20 @@ class AnthropicConfig(AnthropicModelInfo, BaseConfig):
|
|||
if tool.get("type", None) and tool.get("type").startswith(
|
||||
ANTHROPIC_HOSTED_TOOLS.WEB_FETCH.value
|
||||
):
|
||||
headers["anthropic-beta"] = (
|
||||
ANTHROPIC_BETA_HEADER_VALUES.WEB_FETCH_2025_09_10.value
|
||||
self._ensure_beta_header(
|
||||
headers, ANTHROPIC_BETA_HEADER_VALUES.WEB_FETCH_2025_09_10.value
|
||||
)
|
||||
elif tool.get("type", None) and tool.get("type").startswith(
|
||||
ANTHROPIC_HOSTED_TOOLS.MEMORY.value
|
||||
):
|
||||
headers["anthropic-beta"] = (
|
||||
ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value
|
||||
self._ensure_beta_header(
|
||||
headers, ANTHROPIC_BETA_HEADER_VALUES.CONTEXT_MANAGEMENT_2025_06_27.value
|
||||
)
|
||||
if optional_params.get("context_management") is not None:
|
||||
self._ensure_context_management_beta_header(headers)
|
||||
if optional_params.get("output_format") is not None:
|
||||
headers["anthropic-beta"] = (
|
||||
ANTHROPIC_BETA_HEADER_VALUES.STRUCTURED_OUTPUT_2025_09_25.value
|
||||
self._ensure_beta_header(
|
||||
headers, ANTHROPIC_BETA_HEADER_VALUES.STRUCTURED_OUTPUT_2025_09_25.value
|
||||
)
|
||||
return headers
|
||||
|
||||
|
|
|
|||
|
|
@ -0,0 +1,246 @@
|
|||
"""
|
||||
Fake Streaming Iterator for Anthropic Messages
|
||||
|
||||
This module provides a fake streaming iterator that converts non-streaming
|
||||
Anthropic Messages responses into proper streaming format.
|
||||
|
||||
Used when WebSearch interception converts stream=True to stream=False but
|
||||
the LLM doesn't make a tool call, and we need to return a stream to the user.
|
||||
"""
|
||||
|
||||
import json
|
||||
from typing import Any, Dict, List, cast
|
||||
|
||||
from litellm.types.llms.anthropic_messages.anthropic_response import (
|
||||
AnthropicMessagesResponse,
|
||||
)
|
||||
|
||||
|
||||
class FakeAnthropicMessagesStreamIterator:
|
||||
"""
|
||||
Fake streaming iterator for Anthropic Messages responses.
|
||||
|
||||
Used when we need to convert a non-streaming response to a streaming format,
|
||||
such as when WebSearch interception converts stream=True to stream=False but
|
||||
the LLM doesn't make a tool call.
|
||||
|
||||
This creates a proper Anthropic-style streaming response with multiple events:
|
||||
- message_start
|
||||
- content_block_start (for each content block)
|
||||
- content_block_delta (for text content, chunked)
|
||||
- content_block_stop
|
||||
- message_delta (for usage)
|
||||
- message_stop
|
||||
"""
|
||||
|
||||
def __init__(self, response: AnthropicMessagesResponse):
|
||||
self.response = response
|
||||
self.chunks = self._create_streaming_chunks()
|
||||
self.current_index = 0
|
||||
|
||||
def _create_streaming_chunks(self) -> List[bytes]:
|
||||
"""Convert the non-streaming response to streaming chunks"""
|
||||
chunks = []
|
||||
|
||||
# Cast response to dict for easier access
|
||||
response_dict = cast(Dict[str, Any], self.response)
|
||||
|
||||
# 1. message_start event
|
||||
usage = response_dict.get("usage", {})
|
||||
message_start = {
|
||||
"type": "message_start",
|
||||
"message": {
|
||||
"id": response_dict.get("id"),
|
||||
"type": "message",
|
||||
"role": response_dict.get("role", "assistant"),
|
||||
"model": response_dict.get("model"),
|
||||
"content": [],
|
||||
"stop_reason": None,
|
||||
"stop_sequence": None,
|
||||
"usage": {
|
||||
"input_tokens": usage.get("input_tokens", 0) if usage else 0,
|
||||
"output_tokens": 0
|
||||
}
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: message_start\ndata: {json.dumps(message_start)}\n\n".encode())
|
||||
|
||||
# 2-4. For each content block, send start/delta/stop events
|
||||
content_blocks = response_dict.get("content", [])
|
||||
if content_blocks:
|
||||
for index, block in enumerate(content_blocks):
|
||||
# Cast block to dict for easier access
|
||||
block_dict = cast(Dict[str, Any], block)
|
||||
block_type = block_dict.get("type")
|
||||
|
||||
if block_type == "text":
|
||||
# content_block_start
|
||||
content_block_start = {
|
||||
"type": "content_block_start",
|
||||
"index": index,
|
||||
"content_block": {
|
||||
"type": "text",
|
||||
"text": ""
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_start\ndata: {json.dumps(content_block_start)}\n\n".encode())
|
||||
|
||||
# content_block_delta (send full text as one delta for simplicity)
|
||||
text = block_dict.get("text", "")
|
||||
content_block_delta = {
|
||||
"type": "content_block_delta",
|
||||
"index": index,
|
||||
"delta": {
|
||||
"type": "text_delta",
|
||||
"text": text
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_delta\ndata: {json.dumps(content_block_delta)}\n\n".encode())
|
||||
|
||||
# content_block_stop
|
||||
content_block_stop = {
|
||||
"type": "content_block_stop",
|
||||
"index": index
|
||||
}
|
||||
chunks.append(f"event: content_block_stop\ndata: {json.dumps(content_block_stop)}\n\n".encode())
|
||||
|
||||
elif block_type == "thinking":
|
||||
# content_block_start for thinking
|
||||
content_block_start = {
|
||||
"type": "content_block_start",
|
||||
"index": index,
|
||||
"content_block": {
|
||||
"type": "thinking",
|
||||
"thinking": "",
|
||||
"signature": ""
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_start\ndata: {json.dumps(content_block_start)}\n\n".encode())
|
||||
|
||||
# content_block_delta for thinking text
|
||||
thinking_text = block_dict.get("thinking", "")
|
||||
if thinking_text:
|
||||
content_block_delta = {
|
||||
"type": "content_block_delta",
|
||||
"index": index,
|
||||
"delta": {
|
||||
"type": "thinking_delta",
|
||||
"thinking": thinking_text
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_delta\ndata: {json.dumps(content_block_delta)}\n\n".encode())
|
||||
|
||||
# content_block_delta for signature (if present)
|
||||
signature = block_dict.get("signature", "")
|
||||
if signature:
|
||||
signature_delta = {
|
||||
"type": "content_block_delta",
|
||||
"index": index,
|
||||
"delta": {
|
||||
"type": "signature_delta",
|
||||
"signature": signature
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_delta\ndata: {json.dumps(signature_delta)}\n\n".encode())
|
||||
|
||||
# content_block_stop
|
||||
content_block_stop = {
|
||||
"type": "content_block_stop",
|
||||
"index": index
|
||||
}
|
||||
chunks.append(f"event: content_block_stop\ndata: {json.dumps(content_block_stop)}\n\n".encode())
|
||||
|
||||
elif block_type == "redacted_thinking":
|
||||
# content_block_start for redacted_thinking
|
||||
content_block_start = {
|
||||
"type": "content_block_start",
|
||||
"index": index,
|
||||
"content_block": {
|
||||
"type": "redacted_thinking"
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_start\ndata: {json.dumps(content_block_start)}\n\n".encode())
|
||||
|
||||
# content_block_stop (no delta for redacted thinking)
|
||||
content_block_stop = {
|
||||
"type": "content_block_stop",
|
||||
"index": index
|
||||
}
|
||||
chunks.append(f"event: content_block_stop\ndata: {json.dumps(content_block_stop)}\n\n".encode())
|
||||
|
||||
elif block_type == "tool_use":
|
||||
# content_block_start
|
||||
content_block_start = {
|
||||
"type": "content_block_start",
|
||||
"index": index,
|
||||
"content_block": {
|
||||
"type": "tool_use",
|
||||
"id": block_dict.get("id"),
|
||||
"name": block_dict.get("name"),
|
||||
"input": {}
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_start\ndata: {json.dumps(content_block_start)}\n\n".encode())
|
||||
|
||||
# content_block_delta (send input as JSON delta)
|
||||
input_data = block_dict.get("input", {})
|
||||
content_block_delta = {
|
||||
"type": "content_block_delta",
|
||||
"index": index,
|
||||
"delta": {
|
||||
"type": "input_json_delta",
|
||||
"partial_json": json.dumps(input_data)
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: content_block_delta\ndata: {json.dumps(content_block_delta)}\n\n".encode())
|
||||
|
||||
# content_block_stop
|
||||
content_block_stop = {
|
||||
"type": "content_block_stop",
|
||||
"index": index
|
||||
}
|
||||
chunks.append(f"event: content_block_stop\ndata: {json.dumps(content_block_stop)}\n\n".encode())
|
||||
|
||||
# 5. message_delta event (with final usage and stop_reason)
|
||||
message_delta = {
|
||||
"type": "message_delta",
|
||||
"delta": {
|
||||
"stop_reason": response_dict.get("stop_reason"),
|
||||
"stop_sequence": response_dict.get("stop_sequence")
|
||||
},
|
||||
"usage": {
|
||||
"output_tokens": usage.get("output_tokens", 0) if usage else 0
|
||||
}
|
||||
}
|
||||
chunks.append(f"event: message_delta\ndata: {json.dumps(message_delta)}\n\n".encode())
|
||||
|
||||
# 6. message_stop event
|
||||
message_stop = {
|
||||
"type": "message_stop",
|
||||
"usage": usage if usage else {}
|
||||
}
|
||||
chunks.append(f"event: message_stop\ndata: {json.dumps(message_stop)}\n\n".encode())
|
||||
|
||||
return chunks
|
||||
|
||||
def __aiter__(self):
|
||||
return self
|
||||
|
||||
async def __anext__(self):
|
||||
if self.current_index >= len(self.chunks):
|
||||
raise StopAsyncIteration
|
||||
|
||||
chunk = self.chunks[self.current_index]
|
||||
self.current_index += 1
|
||||
return chunk
|
||||
|
||||
def __iter__(self):
|
||||
return self
|
||||
|
||||
def __next__(self):
|
||||
if self.current_index >= len(self.chunks):
|
||||
raise StopIteration
|
||||
|
||||
chunk = self.chunks[self.current_index]
|
||||
self.current_index += 1
|
||||
return chunk
|
||||
|
|
@ -33,6 +33,70 @@ base_llm_http_handler = BaseLLMHTTPHandler()
|
|||
#################################################
|
||||
|
||||
|
||||
async def _execute_pre_request_hooks(
|
||||
model: str,
|
||||
messages: List[Dict],
|
||||
tools: Optional[List[Dict]],
|
||||
stream: Optional[bool],
|
||||
custom_llm_provider: Optional[str],
|
||||
**kwargs,
|
||||
) -> Dict:
|
||||
"""
|
||||
Execute pre-request hooks from CustomLogger callbacks.
|
||||
|
||||
Allows CustomLoggers to modify request parameters before the API call.
|
||||
Used for WebSearch tool conversion, stream modification, etc.
|
||||
|
||||
Args:
|
||||
model: Model name
|
||||
messages: List of messages
|
||||
tools: Optional tools list
|
||||
stream: Optional stream flag
|
||||
custom_llm_provider: Provider name (if not set, will be extracted from model)
|
||||
**kwargs: Additional request parameters
|
||||
|
||||
Returns:
|
||||
Dict containing all (potentially modified) request parameters including tools, stream
|
||||
"""
|
||||
# If custom_llm_provider not provided, extract from model
|
||||
if not custom_llm_provider:
|
||||
try:
|
||||
_, custom_llm_provider, _, _ = litellm.get_llm_provider(model=model)
|
||||
except Exception:
|
||||
# If extraction fails, continue without provider
|
||||
pass
|
||||
|
||||
# Build complete request kwargs dict
|
||||
request_kwargs = {
|
||||
"tools": tools,
|
||||
"stream": stream,
|
||||
"litellm_params": {
|
||||
"custom_llm_provider": custom_llm_provider,
|
||||
},
|
||||
**kwargs,
|
||||
}
|
||||
|
||||
if not litellm.callbacks:
|
||||
return request_kwargs
|
||||
|
||||
from litellm.integrations.custom_logger import CustomLogger as _CustomLogger
|
||||
|
||||
for callback in litellm.callbacks:
|
||||
if not isinstance(callback, _CustomLogger):
|
||||
continue
|
||||
|
||||
# Call the pre-request hook
|
||||
modified_kwargs = await callback.async_pre_request_hook(
|
||||
model, messages, request_kwargs
|
||||
)
|
||||
|
||||
# If hook returned modified kwargs, use them
|
||||
if modified_kwargs is not None:
|
||||
request_kwargs = modified_kwargs
|
||||
|
||||
return request_kwargs
|
||||
|
||||
|
||||
@client
|
||||
async def anthropic_messages(
|
||||
max_tokens: int,
|
||||
|
|
@ -57,39 +121,24 @@ async def anthropic_messages(
|
|||
"""
|
||||
Async: Make llm api request in Anthropic /messages API spec
|
||||
"""
|
||||
# WebSearch Interception: Convert stream=True to stream=False if WebSearch interception is enabled
|
||||
# This allows transparent server-side agentic loop execution for streaming requests
|
||||
if stream and tools and any(t.get("name") == "WebSearch" for t in tools):
|
||||
# Extract provider using litellm's helper function
|
||||
try:
|
||||
_, provider, _, _ = litellm.get_llm_provider(
|
||||
model=model,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
api_base=api_base,
|
||||
api_key=api_key,
|
||||
)
|
||||
except Exception:
|
||||
# Fallback to simple split if helper fails
|
||||
provider = model.split("/")[0] if "/" in model else ""
|
||||
# Execute pre-request hooks to allow CustomLoggers to modify request
|
||||
request_kwargs = await _execute_pre_request_hooks(
|
||||
model=model,
|
||||
messages=messages,
|
||||
tools=tools,
|
||||
stream=stream,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
# Check if WebSearch interception is enabled in callbacks
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.integrations.websearch_interception import (
|
||||
WebSearchInterceptionLogger,
|
||||
)
|
||||
if litellm.callbacks:
|
||||
for callback in litellm.callbacks:
|
||||
if isinstance(callback, WebSearchInterceptionLogger):
|
||||
# Check if provider is enabled for interception
|
||||
if provider in callback.enabled_providers:
|
||||
verbose_logger.debug(
|
||||
f"WebSearchInterception: Converting stream=True to stream=False for WebSearch interception "
|
||||
f"(provider={provider})"
|
||||
)
|
||||
stream = False
|
||||
break
|
||||
# Extract modified parameters
|
||||
tools = request_kwargs.pop("tools", tools)
|
||||
stream = request_kwargs.pop("stream", stream)
|
||||
# Remove litellm_params from kwargs (only needed for hooks)
|
||||
request_kwargs.pop("litellm_params", None)
|
||||
# Merge back any other modifications
|
||||
kwargs.update(request_kwargs)
|
||||
|
||||
local_vars = locals()
|
||||
loop = asyncio.get_event_loop()
|
||||
kwargs["is_async"] = True
|
||||
|
||||
|
|
@ -206,6 +255,11 @@ def anthropic_messages_handler(
|
|||
"model": original_model,
|
||||
"custom_llm_provider": custom_llm_provider,
|
||||
}
|
||||
|
||||
# Check if stream was converted for WebSearch interception
|
||||
# This is set in the async wrapper above when stream=True is converted to stream=False
|
||||
if kwargs.get("_websearch_interception_converted_stream", False):
|
||||
litellm_logging_obj.model_call_details["websearch_interception_converted_stream"] = True
|
||||
|
||||
if litellm_params.mock_response and isinstance(litellm_params.mock_response, str):
|
||||
|
||||
|
|
|
|||
|
|
@ -88,7 +88,7 @@ class AzureFoundryFlux2ImageEditConfig(OpenAIImageEditConfig):
|
|||
self,
|
||||
model: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image: Optional[FileTypes],
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
headers: dict,
|
||||
|
|
@ -102,6 +102,9 @@ class AzureFoundryFlux2ImageEditConfig(OpenAIImageEditConfig):
|
|||
if prompt is None:
|
||||
raise ValueError("FLUX 2 image edit requires a prompt.")
|
||||
|
||||
if image is None:
|
||||
raise ValueError("FLUX 2 image edit requires an image.")
|
||||
|
||||
image_b64 = self._convert_image_to_base64(image)
|
||||
|
||||
# Build request body with required params
|
||||
|
|
|
|||
|
|
@ -93,7 +93,7 @@ class BaseImageEditConfig(ABC):
|
|||
self,
|
||||
model: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image: Optional[FileTypes],
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
headers: dict,
|
||||
|
|
|
|||
|
|
@ -62,7 +62,7 @@ class BedrockImageEdit(BaseAWSLLM):
|
|||
self,
|
||||
model: str,
|
||||
image: list,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
model_response: ImageResponse,
|
||||
optional_params: dict,
|
||||
logging_obj: LitellmLogging,
|
||||
|
|
@ -127,7 +127,7 @@ class BedrockImageEdit(BaseAWSLLM):
|
|||
timeout: Optional[Union[float, httpx.Timeout]],
|
||||
model: str,
|
||||
logging_obj: LitellmLogging,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
model_response: ImageResponse,
|
||||
client: Optional[AsyncHTTPHandler] = None,
|
||||
) -> ImageResponse:
|
||||
|
|
@ -163,7 +163,7 @@ class BedrockImageEdit(BaseAWSLLM):
|
|||
self,
|
||||
model: str,
|
||||
image: list,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
optional_params: dict,
|
||||
api_base: Optional[str],
|
||||
extra_headers: Optional[dict],
|
||||
|
|
@ -176,7 +176,7 @@ class BedrockImageEdit(BaseAWSLLM):
|
|||
Args:
|
||||
model (str): The model to use for the image edit
|
||||
image (list): The images to edit
|
||||
prompt (str): The prompt for the edit
|
||||
prompt (Optional[str]): The prompt for the edit
|
||||
optional_params (dict): The optional parameters for the image edit
|
||||
api_base (Optional[str]): The base URL for the Bedrock API
|
||||
extra_headers (Optional[dict]): The extra headers to include in the request
|
||||
|
|
@ -248,7 +248,7 @@ class BedrockImageEdit(BaseAWSLLM):
|
|||
self,
|
||||
model: str,
|
||||
image: list,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
optional_params: dict,
|
||||
) -> dict:
|
||||
"""
|
||||
|
|
@ -276,7 +276,7 @@ class BedrockImageEdit(BaseAWSLLM):
|
|||
model_response: ImageResponse,
|
||||
model: str,
|
||||
logging_obj: LitellmLogging,
|
||||
prompt: str,
|
||||
prompt: Optional[str],
|
||||
response: httpx.Response,
|
||||
data: dict,
|
||||
) -> ImageResponse:
|
||||
|
|
|
|||
|
|
@ -150,11 +150,11 @@ class BedrockStabilityImageEditConfig(BaseImageEditConfig):
|
|||
|
||||
return mapped_params
|
||||
|
||||
def transform_image_edit_request(
|
||||
def transform_image_edit_request( #noqa: PLR0915
|
||||
self,
|
||||
model: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image: Optional[FileTypes],
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
headers: dict,
|
||||
|
|
@ -164,32 +164,38 @@ class BedrockStabilityImageEditConfig(BaseImageEditConfig):
|
|||
|
||||
Returns the request body dict that will be JSON-encoded by the handler.
|
||||
"""
|
||||
if prompt is None:
|
||||
raise ValueError("Bedrock Stability image edit requires a prompt.")
|
||||
|
||||
# Build Bedrock Stability request
|
||||
data: Dict[str, Any] = {
|
||||
"prompt": prompt,
|
||||
"output_format": "png", # Default to PNG
|
||||
}
|
||||
|
||||
# Convert image to base64
|
||||
image_b64: str
|
||||
if hasattr(image, 'read') and callable(getattr(image, 'read', None)):
|
||||
# File-like object (e.g., BufferedReader from open())
|
||||
image_bytes = image.read() # type: ignore
|
||||
image_b64 = base64.b64encode(image_bytes).decode('utf-8') # type: ignore
|
||||
elif isinstance(image, bytes):
|
||||
# Raw bytes
|
||||
image_b64 = base64.b64encode(image).decode('utf-8')
|
||||
elif isinstance(image, str):
|
||||
# Already a base64 string
|
||||
image_b64 = image
|
||||
else:
|
||||
# Try to handle as bytes
|
||||
image_b64 = base64.b64encode(bytes(image)).decode('utf-8') # type: ignore
|
||||
# Add prompt only if provided (some models don't require it)
|
||||
if prompt is not None and prompt != "":
|
||||
data["prompt"] = prompt
|
||||
|
||||
# Convert image to base64 if provided
|
||||
if image is not None:
|
||||
image_b64: str
|
||||
if hasattr(image, 'read') and callable(getattr(image, 'read', None)):
|
||||
# File-like object (e.g., BufferedReader from open())
|
||||
image_bytes = image.read() # type: ignore
|
||||
image_b64 = base64.b64encode(image_bytes).decode('utf-8') # type: ignore
|
||||
elif isinstance(image, bytes):
|
||||
# Raw bytes
|
||||
image_b64 = base64.b64encode(image).decode('utf-8')
|
||||
elif isinstance(image, str):
|
||||
# Already a base64 string
|
||||
image_b64 = image
|
||||
else:
|
||||
# Try to handle as bytes
|
||||
image_b64 = base64.b64encode(bytes(image)).decode('utf-8') # type: ignore
|
||||
|
||||
data["image"] = image_b64
|
||||
# For style-transfer models, map image to init_image
|
||||
model_lower = model.lower()
|
||||
if "style-transfer" in model_lower:
|
||||
data["init_image"] = image_b64
|
||||
else:
|
||||
data["image"] = image_b64
|
||||
|
||||
# Add optional params (already mapped in map_openai_params)
|
||||
for key, value in image_edit_optional_request_params.items(): # type: ignore
|
||||
|
|
@ -221,30 +227,43 @@ class BedrockStabilityImageEditConfig(BaseImageEditConfig):
|
|||
file_b64 = str(file_bytes)
|
||||
data[key] = file_b64
|
||||
continue
|
||||
|
||||
# Supported text fields
|
||||
if key in [
|
||||
"negative_prompt",
|
||||
"aspect_ratio",
|
||||
"seed",
|
||||
"output_format",
|
||||
"model",
|
||||
"mode",
|
||||
|
||||
# Numeric fields that need to be converted to int/float
|
||||
numeric_int_fields = ["left", "right", "up", "down", "seed"]
|
||||
numeric_float_fields = [
|
||||
"strength",
|
||||
"style_preset",
|
||||
"creativity",
|
||||
"control_strength",
|
||||
"grow_mask",
|
||||
"left",
|
||||
"right",
|
||||
"up",
|
||||
"down",
|
||||
"select_prompt",
|
||||
"search_prompt",
|
||||
"fidelity",
|
||||
"composition_fidelity",
|
||||
"style_strength",
|
||||
"change_strength",
|
||||
]
|
||||
|
||||
if key in numeric_int_fields:
|
||||
# Convert to int (these are pixel values for outpaint)
|
||||
try:
|
||||
data[key] = int(value) # type: ignore
|
||||
except (ValueError, TypeError):
|
||||
data[key] = value # type: ignore
|
||||
elif key in numeric_float_fields:
|
||||
# Convert to float
|
||||
try:
|
||||
data[key] = float(value) # type: ignore
|
||||
except (ValueError, TypeError):
|
||||
data[key] = value # type: ignore
|
||||
|
||||
# Supported text fields
|
||||
elif key in [
|
||||
"negative_prompt",
|
||||
"aspect_ratio",
|
||||
"output_format",
|
||||
"model",
|
||||
"mode",
|
||||
"style_preset",
|
||||
"select_prompt",
|
||||
"search_prompt",
|
||||
]:
|
||||
data[key] = value # type: ignore
|
||||
|
||||
|
|
|
|||
|
|
@ -3080,10 +3080,8 @@ class BaseLLMHTTPHandler:
|
|||
transformed_request, bytes
|
||||
):
|
||||
# Handle traditional file uploads
|
||||
# Ensure transformed_request is a string for httpx compatibility
|
||||
if isinstance(transformed_request, bytes):
|
||||
transformed_request = transformed_request.decode("utf-8")
|
||||
|
||||
# Note: transformed_request can be bytes (for binary files like PDFs)
|
||||
# or str (for text files like JSONL). httpx handles both correctly.
|
||||
# Use the HTTP method specified by the provider config
|
||||
http_method = provider_config.file_upload_http_method.upper()
|
||||
if http_method == "PUT":
|
||||
|
|
@ -4418,6 +4416,41 @@ class BaseLLMHTTPHandler:
|
|||
f"LiteLLM.AgenticHookError: Exception in agentic completion hooks: {str(e)}"
|
||||
)
|
||||
|
||||
# Check if we need to convert response to fake stream
|
||||
# This happens when:
|
||||
# 1. Stream was originally True but converted to False for WebSearch interception
|
||||
# 2. No agentic loop ran (LLM didn't use the tool)
|
||||
# 3. We have a non-streaming response that needs to be converted to streaming
|
||||
websearch_converted_stream = (
|
||||
logging_obj.model_call_details.get("websearch_interception_converted_stream", False)
|
||||
if logging_obj is not None
|
||||
else False
|
||||
)
|
||||
|
||||
if websearch_converted_stream:
|
||||
from typing import cast
|
||||
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.llms.anthropic.experimental_pass_through.messages.fake_stream_iterator import (
|
||||
FakeAnthropicMessagesStreamIterator,
|
||||
)
|
||||
from litellm.types.llms.anthropic_messages.anthropic_response import (
|
||||
AnthropicMessagesResponse,
|
||||
)
|
||||
|
||||
verbose_logger.debug(
|
||||
"WebSearchInterception: No tool call made, converting non-streaming response to fake stream"
|
||||
)
|
||||
|
||||
# Convert the non-streaming response to a fake stream
|
||||
# The response should be an AnthropicMessagesResponse (dict)
|
||||
if isinstance(response, dict):
|
||||
# Create a fake streaming iterator
|
||||
fake_stream = FakeAnthropicMessagesStreamIterator(
|
||||
response=cast(AnthropicMessagesResponse, response)
|
||||
)
|
||||
return fake_stream
|
||||
|
||||
return None
|
||||
|
||||
def _handle_error(
|
||||
|
|
|
|||
|
|
@ -81,21 +81,23 @@ class GeminiImageEditConfig(BaseImageEditConfig):
|
|||
self,
|
||||
model: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image: Optional[FileTypes],
|
||||
image_edit_optional_request_params: Dict[str, Any],
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
headers: dict,
|
||||
) -> Tuple[Dict[str, Any], Optional[RequestFiles]]:
|
||||
inline_parts = self._prepare_inline_image_parts(image)
|
||||
inline_parts = self._prepare_inline_image_parts(image) if image else []
|
||||
if not inline_parts:
|
||||
raise ValueError("Gemini image edit requires at least one image.")
|
||||
|
||||
if prompt is None:
|
||||
raise ValueError("Gemini image edit requires a prompt.")
|
||||
# Build parts list with image and prompt (if provided)
|
||||
parts = inline_parts.copy()
|
||||
if prompt is not None and prompt != "":
|
||||
parts.append({"text": prompt})
|
||||
|
||||
contents = [
|
||||
{
|
||||
"parts": inline_parts + [{"text": prompt}],
|
||||
"parts": parts,
|
||||
}
|
||||
]
|
||||
|
||||
|
|
|
|||
|
|
@ -31,7 +31,7 @@ class DallE2ImageEditConfig(OpenAIImageEditConfig):
|
|||
self,
|
||||
model: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image: Optional[FileTypes],
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
headers: dict,
|
||||
|
|
@ -40,18 +40,20 @@ class DallE2ImageEditConfig(OpenAIImageEditConfig):
|
|||
Transform image edit request for DALL-E-2.
|
||||
|
||||
DALL-E-2 only accepts a single image with field name "image" (not "image[]").
|
||||
"""
|
||||
if prompt is None:
|
||||
raise ValueError("DALL-E-2 image edit requires a prompt.")
|
||||
|
||||
request = ImageEditRequestParams(
|
||||
model=model,
|
||||
image=image,
|
||||
prompt=prompt,
|
||||
"""
|
||||
request_params = {
|
||||
"model": model,
|
||||
**image_edit_optional_request_params,
|
||||
)
|
||||
}
|
||||
if image is not None:
|
||||
request_params["image"] = image
|
||||
if prompt is not None:
|
||||
request_params["prompt"] = prompt
|
||||
|
||||
request = ImageEditRequestParams(**request_params)
|
||||
request_dict = cast(Dict, request)
|
||||
|
||||
|
||||
#########################################################
|
||||
# Separate images and masks as `files` and send other parameters as `data`
|
||||
#########################################################
|
||||
|
|
|
|||
|
|
@ -80,7 +80,7 @@ class OpenAIImageEditConfig(BaseImageEditConfig):
|
|||
self,
|
||||
model: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image: Optional[FileTypes],
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
headers: dict,
|
||||
|
|
@ -91,15 +91,17 @@ class OpenAIImageEditConfig(BaseImageEditConfig):
|
|||
Handles multipart/form-data for images. Uses "image[]" field name
|
||||
to support multiple images (e.g., for gpt-image-1).
|
||||
"""
|
||||
if prompt is None:
|
||||
raise ValueError("OpenAI image edit requires a prompt.")
|
||||
|
||||
request = ImageEditRequestParams(
|
||||
model=model,
|
||||
image=image,
|
||||
prompt=prompt,
|
||||
# Build request params, only including non-None values
|
||||
request_params = {
|
||||
"model": model,
|
||||
**image_edit_optional_request_params,
|
||||
)
|
||||
}
|
||||
if image is not None:
|
||||
request_params["image"] = image
|
||||
if prompt is not None:
|
||||
request_params["prompt"] = prompt
|
||||
|
||||
request = ImageEditRequestParams(**request_params)
|
||||
request_dict = cast(Dict, request)
|
||||
|
||||
#########################################################
|
||||
|
|
|
|||
|
|
@ -102,7 +102,7 @@ class RecraftImageEditConfig(BaseImageEditConfig):
|
|||
self,
|
||||
model: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image: Optional[FileTypes],
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
headers: dict,
|
||||
|
|
@ -114,15 +114,15 @@ class RecraftImageEditConfig(BaseImageEditConfig):
|
|||
https://www.recraft.ai/docs#image-to-image
|
||||
"""
|
||||
|
||||
if prompt is None:
|
||||
raise ValueError("Recraft image edit requires a prompt.")
|
||||
|
||||
request_body: RecraftImageEditRequestParams = RecraftImageEditRequestParams(
|
||||
model=model,
|
||||
prompt=prompt,
|
||||
strength=image_edit_optional_request_params.pop("strength", self.DEFAULT_STRENGTH),
|
||||
request_params = {
|
||||
"model": model,
|
||||
"strength": image_edit_optional_request_params.pop("strength", self.DEFAULT_STRENGTH),
|
||||
**image_edit_optional_request_params,
|
||||
)
|
||||
}
|
||||
if prompt is not None:
|
||||
request_params["prompt"] = prompt
|
||||
|
||||
request_body = RecraftImageEditRequestParams(**request_params)
|
||||
request_dict = cast(Dict, request_body)
|
||||
#########################################################
|
||||
# Reuse OpenAI logic: Separate images as `files` and send other parameters as `data`
|
||||
|
|
|
|||
|
|
@ -83,19 +83,27 @@ async def async_handle_prediction_response_streaming(
|
|||
await asyncio.sleep(
|
||||
REPLICATE_POLLING_DELAY_SECONDS
|
||||
) # prevent being rate limited by replicate
|
||||
print_verbose(f"replicate: polling endpoint: {prediction_url}")
|
||||
response = await http_client.get(prediction_url, headers=headers)
|
||||
if response.status_code == 200:
|
||||
response_data = response.json()
|
||||
status = response_data["status"]
|
||||
if "output" in response_data:
|
||||
status = response_data.get("status", "")
|
||||
# Check that "output" exists and is not None or empty
|
||||
output_present = "output" in response_data and response_data["output"] is not None
|
||||
if output_present:
|
||||
try:
|
||||
output_string = "".join(response_data["output"])
|
||||
# If output is None or not a list, treat as empty string
|
||||
if isinstance(response_data["output"], list):
|
||||
output_string = "".join(response_data["output"])
|
||||
elif response_data["output"] is None:
|
||||
output_string = ""
|
||||
else:
|
||||
# fallback for other types; convert to string safely
|
||||
output_string = str(response_data["output"])
|
||||
except Exception:
|
||||
raise ReplicateError(
|
||||
status_code=422,
|
||||
message="Unable to parse response. Got={}".format(
|
||||
response_data["output"]
|
||||
response_data.get("output", None)
|
||||
),
|
||||
headers=response.headers,
|
||||
)
|
||||
|
|
@ -103,7 +111,7 @@ async def async_handle_prediction_response_streaming(
|
|||
print_verbose(f"New chunk: {new_output}")
|
||||
yield {"output": new_output, "status": status}
|
||||
previous_output = output_string
|
||||
status = response_data["status"]
|
||||
status = response_data.get("status", "")
|
||||
if status == "failed":
|
||||
replicate_error = response_data.get("error", "")
|
||||
raise ReplicateError(
|
||||
|
|
|
|||
|
|
@ -171,7 +171,7 @@ class StabilityImageEditConfig(BaseImageEditConfig):
|
|||
self,
|
||||
model: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image: Optional[FileTypes],
|
||||
image_edit_optional_request_params: Dict,
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
headers: dict,
|
||||
|
|
@ -190,11 +190,14 @@ class StabilityImageEditConfig(BaseImageEditConfig):
|
|||
}
|
||||
|
||||
# Add prompt only if provided (some Stability endpoints don't require it)
|
||||
if prompt is not None:
|
||||
if prompt is not None and prompt != "":
|
||||
data["prompt"] = prompt
|
||||
# Handle image parameter - could be a single file or list
|
||||
image_file = image[0] if isinstance(image, list) else image # type: ignore
|
||||
files: Dict[str, Any] = {"image": image_file}
|
||||
files: Dict[str, Any] = {}
|
||||
if image is not None:
|
||||
image_file = image[0] if isinstance(image, list) else image # type: ignore
|
||||
files["image"] = image_file
|
||||
|
||||
# Add optional params (already mapped in map_openai_params)
|
||||
for key, value in image_edit_optional_request_params.items(): # type: ignore
|
||||
|
|
|
|||
|
|
@ -453,9 +453,10 @@ def _build_vertex_schema(parameters: dict, add_property_ordering: bool = False):
|
|||
valid_schema_fields = set(get_type_hints(Schema).keys())
|
||||
|
||||
defs = parameters.pop("$defs", {})
|
||||
# flatten the defs
|
||||
for name, value in defs.items():
|
||||
unpack_defs(value, defs)
|
||||
# Expand $ref references in parameters using the definitions
|
||||
# Note: We don't pre-flatten defs as that causes exponential memory growth
|
||||
# with circular references (see issue #19098). unpack_defs handles nested
|
||||
# refs recursively and correctly detects/skips circular references.
|
||||
unpack_defs(parameters, defs)
|
||||
|
||||
# 5. Nullable fields:
|
||||
|
|
|
|||
|
|
@ -152,22 +152,24 @@ class VertexAIGeminiImageEditConfig(BaseImageEditConfig, VertexLLM):
|
|||
self,
|
||||
model: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image: Optional[FileTypes],
|
||||
image_edit_optional_request_params: Dict[str, Any],
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
headers: dict,
|
||||
) -> Tuple[Dict[str, Any], Optional[RequestFiles]]:
|
||||
inline_parts = self._prepare_inline_image_parts(image)
|
||||
inline_parts = self._prepare_inline_image_parts(image) if image else []
|
||||
if not inline_parts:
|
||||
raise ValueError("Vertex AI Gemini image edit requires at least one image.")
|
||||
|
||||
if prompt is None:
|
||||
raise ValueError("Vertex AI Gemini image edit requires a prompt.")
|
||||
# Build parts list with image and prompt (if provided)
|
||||
parts = inline_parts.copy()
|
||||
if prompt is not None and prompt != "":
|
||||
parts.append({"text": prompt})
|
||||
|
||||
# Correct format for Vertex AI Gemini image editing
|
||||
contents = {
|
||||
"role": "USER",
|
||||
"parts": inline_parts + [{"text": prompt}]
|
||||
"parts": parts
|
||||
}
|
||||
|
||||
request_body: Dict[str, Any] = {"contents": contents}
|
||||
|
|
|
|||
|
|
@ -144,7 +144,7 @@ class VertexAIImagenImageEditConfig(BaseImageEditConfig, VertexLLM):
|
|||
self,
|
||||
model: str,
|
||||
prompt: Optional[str],
|
||||
image: FileTypes,
|
||||
image: Optional[FileTypes],
|
||||
image_edit_optional_request_params: Dict[str, Any],
|
||||
litellm_params: GenericLiteLLMParams,
|
||||
headers: dict,
|
||||
|
|
|
|||
|
|
@ -7857,6 +7857,24 @@
|
|||
"supports_tool_choice": true,
|
||||
"supports_vision": true
|
||||
},
|
||||
"dall-e-2": {
|
||||
"input_cost_per_image": 0.02,
|
||||
"litellm_provider": "openai",
|
||||
"mode": "image_generation",
|
||||
"supported_endpoints": [
|
||||
"/v1/images/generations",
|
||||
"/v1/images/edits",
|
||||
"/v1/images/variations"
|
||||
]
|
||||
},
|
||||
"dall-e-3": {
|
||||
"input_cost_per_image": 0.04,
|
||||
"litellm_provider": "openai",
|
||||
"mode": "image_generation",
|
||||
"supported_endpoints": [
|
||||
"/v1/images/generations"
|
||||
]
|
||||
},
|
||||
"deepseek-chat": {
|
||||
"cache_read_input_token_cost": 2.8e-08,
|
||||
"input_cost_per_token": 2.8e-07,
|
||||
|
|
|
|||
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue