mirror of
https://github.com/BerriAI/litellm.git
synced 2026-10-06 02:48:13 +00:00
Merge branch 'main' of https://github.com/otaviofbrito/litellm into chore/handle-count-tokens-errors
This commit is contained in:
 Otavio Brito
commit
151c76a35f
1111 changed files with 60652 additions and 13106 deletions
|
|
@ -112,6 +112,24 @@ jobs:
|
|||
python -m mypy .
|
||||
cd ..
|
||||
no_output_timeout: 10m
|
||||
|
||||
semgrep:
|
||||
docker:
|
||||
- image: cimg/python:3.12
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
steps:
|
||||
- checkout
|
||||
- setup_google_dns
|
||||
- run:
|
||||
name: Install Semgrep
|
||||
command: pip install semgrep
|
||||
- run:
|
||||
name: Run Semgrep (custom rules only)
|
||||
command: semgrep scan --config .semgrep/rules . --error
|
||||
|
||||
local_testing_part1:
|
||||
docker:
|
||||
- image: cimg/python:3.12
|
||||
|
|
@ -1638,7 +1656,7 @@ jobs:
|
|||
- search_coverage.xml
|
||||
- search_coverage
|
||||
# Split litellm_mapped_tests into 3 parallel jobs for 3x faster execution
|
||||
litellm_mapped_tests_proxy:
|
||||
litellm_mapped_tests_proxy_part1:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
|
|
@ -1649,23 +1667,53 @@ jobs:
|
|||
steps:
|
||||
- setup_litellm_test_deps
|
||||
- run:
|
||||
name: Run proxy tests
|
||||
name: Run proxy tests part 1 (high-volume directories)
|
||||
command: |
|
||||
prisma generate
|
||||
python -m pytest tests/test_litellm/proxy --cov=litellm --cov-report=xml --junitxml=test-results/junit-proxy.xml --durations=10 -n 16 --maxfail=5 --timeout=300 -vv --log-cli-level=WARNING
|
||||
no_output_timeout: 120m
|
||||
export PYTHONUNBUFFERED=1
|
||||
python -m pytest tests/test_litellm/proxy/guardrails tests/test_litellm/proxy/management_endpoints tests/test_litellm/proxy/_experimental tests/test_litellm/proxy/client tests/test_litellm/proxy/auth --cov=litellm --cov-report=xml --junitxml=test-results/junit-proxy-part1.xml --durations=10 -n 8 --maxfail=5 --timeout=60 -vv --log-cli-level=WARNING -r A
|
||||
no_output_timeout: 60m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml litellm_proxy_tests_coverage.xml
|
||||
mv .coverage litellm_proxy_tests_coverage
|
||||
mv coverage.xml litellm_proxy_tests_part1_coverage.xml
|
||||
mv .coverage litellm_proxy_tests_part1_coverage
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm_proxy_tests_coverage.xml
|
||||
- litellm_proxy_tests_coverage
|
||||
- litellm_proxy_tests_part1_coverage.xml
|
||||
- litellm_proxy_tests_part1_coverage
|
||||
litellm_mapped_tests_proxy_part2:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
resource_class: xlarge
|
||||
steps:
|
||||
- setup_litellm_test_deps
|
||||
- run:
|
||||
name: Run proxy tests part 2 (all other tests)
|
||||
command: |
|
||||
prisma generate
|
||||
export PYTHONUNBUFFERED=1
|
||||
python -m pytest tests/test_litellm/proxy --ignore=tests/test_litellm/proxy/guardrails --ignore=tests/test_litellm/proxy/management_endpoints --ignore=tests/test_litellm/proxy/_experimental --ignore=tests/test_litellm/proxy/client --ignore=tests/test_litellm/proxy/auth --cov=litellm --cov-report=xml --junitxml=test-results/junit-proxy-part2.xml --durations=10 -n 8 --maxfail=5 --timeout=60 -vv --log-cli-level=WARNING -r A
|
||||
no_output_timeout: 60m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml litellm_proxy_tests_part2_coverage.xml
|
||||
mv .coverage litellm_proxy_tests_part2_coverage
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm_proxy_tests_part2_coverage.xml
|
||||
- litellm_proxy_tests_part2_coverage
|
||||
litellm_mapped_tests_llms:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
|
|
@ -1706,7 +1754,7 @@ jobs:
|
|||
- run:
|
||||
name: Run core tests
|
||||
command: |
|
||||
python -m pytest tests/test_litellm --ignore=tests/test_litellm/proxy --ignore=tests/test_litellm/llms --ignore=tests/test_litellm/integrations --ignore=tests/test_litellm/litellm_core_utils --cov=litellm --cov-report=xml --junitxml=test-results/junit-core.xml --durations=10 -n 16 --maxfail=5 --timeout=300 -vv --log-cli-level=WARNING
|
||||
python -m pytest tests/test_litellm --ignore=tests/test_litellm/proxy --ignore=tests/test_litellm/llms --ignore=tests/test_litellm/integrations --ignore=tests/test_litellm/litellm_core_utils --ignore=tests/test_litellm/experimental_mcp_client --cov=litellm --cov-report=xml --junitxml=test-results/junit-core.xml --durations=10 -n 16 --maxfail=5 --timeout=300 -vv --log-cli-level=WARNING
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
|
|
@ -1747,6 +1795,33 @@ jobs:
|
|||
paths:
|
||||
- litellm_core_utils_tests_coverage.xml
|
||||
- litellm_core_utils_tests_coverage
|
||||
litellm_mapped_tests_mcps:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
auth:
|
||||
username: ${DOCKERHUB_USERNAME}
|
||||
password: ${DOCKERHUB_PASSWORD}
|
||||
working_directory: ~/project
|
||||
resource_class: xlarge
|
||||
steps:
|
||||
- setup_litellm_test_deps
|
||||
- run:
|
||||
name: Run MCP client tests
|
||||
command: |
|
||||
python -m pytest tests/test_litellm/experimental_mcp_client --cov=litellm --cov-report=xml --junitxml=test-results/junit-mcps.xml --durations=10 -n 4 --maxfail=5 --timeout=300 -vv --log-cli-level=WARNING
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
command: |
|
||||
mv coverage.xml litellm_mcps_tests_coverage.xml
|
||||
mv .coverage litellm_mcps_tests_coverage
|
||||
- store_test_results:
|
||||
path: test-results
|
||||
- persist_to_workspace:
|
||||
root: .
|
||||
paths:
|
||||
- litellm_mcps_tests_coverage.xml
|
||||
- litellm_mcps_tests_coverage
|
||||
litellm_mapped_tests_integrations:
|
||||
docker:
|
||||
- image: cimg/python:3.11
|
||||
|
|
@ -3579,9 +3654,11 @@ jobs:
|
|||
-p 4000:4000 \
|
||||
-e DATABASE_URL=postgresql://postgres:postgres@host.docker.internal:5432/circle_test \
|
||||
-e LITELLM_MASTER_KEY="sk-1234" \
|
||||
-e ANTHROPIC_API_KEY=$ANTHROPIC_API_KEY \
|
||||
-e AWS_ACCESS_KEY_ID=$AWS_ACCESS_KEY_ID \
|
||||
-e AWS_SECRET_ACCESS_KEY=$AWS_SECRET_ACCESS_KEY \
|
||||
-e AWS_REGION_NAME="us-east-1" \
|
||||
-e LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS="True" \
|
||||
--add-host host.docker.internal:host-gateway \
|
||||
--name my-app \
|
||||
-v $(pwd)/tests/proxy_e2e_anthropic_messages_tests/test_config.yaml:/app/config.yaml \
|
||||
|
|
@ -3634,7 +3711,7 @@ jobs:
|
|||
python -m venv venv
|
||||
. venv/bin/activate
|
||||
pip install coverage
|
||||
coverage combine llm_translation_coverage realtime_translation_coverage llm_responses_api_coverage ocr_coverage search_coverage mcp_coverage logging_coverage audio_coverage litellm_router_coverage litellm_router_unit_coverage local_testing_part1_coverage local_testing_part2_coverage litellm_assistants_api_coverage auth_ui_unit_tests_coverage langfuse_coverage caching_coverage litellm_proxy_unit_tests_part1_coverage litellm_proxy_unit_tests_part2_coverage image_gen_coverage pass_through_unit_tests_coverage batches_coverage litellm_security_tests_coverage guardrails_coverage litellm_mapped_tests_coverage
|
||||
coverage combine llm_translation_coverage realtime_translation_coverage llm_responses_api_coverage ocr_coverage search_coverage mcp_coverage litellm_mcps_tests_coverage logging_coverage audio_coverage litellm_router_coverage litellm_router_unit_coverage local_testing_part1_coverage local_testing_part2_coverage litellm_assistants_api_coverage auth_ui_unit_tests_coverage langfuse_coverage caching_coverage litellm_proxy_unit_tests_part1_coverage litellm_proxy_unit_tests_part2_coverage image_gen_coverage pass_through_unit_tests_coverage batches_coverage litellm_security_tests_coverage guardrails_coverage litellm_mapped_tests_coverage
|
||||
coverage xml
|
||||
- codecov/upload:
|
||||
file: ./coverage.xml
|
||||
|
|
@ -4118,6 +4195,12 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- semgrep:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- local_testing_part1:
|
||||
filters:
|
||||
branches:
|
||||
|
|
@ -4368,7 +4451,13 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_mapped_tests_proxy:
|
||||
- litellm_mapped_tests_proxy_part1:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_mapped_tests_proxy_part2:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
|
|
@ -4386,6 +4475,12 @@ workflows:
|
|||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_mapped_tests_mcps:
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- /litellm_.*/
|
||||
- litellm_mapped_tests_integrations:
|
||||
filters:
|
||||
branches:
|
||||
|
|
@ -4445,9 +4540,11 @@ workflows:
|
|||
- llm_responses_api_testing
|
||||
- ocr_testing
|
||||
- search_testing
|
||||
- litellm_mapped_tests_proxy
|
||||
- litellm_mapped_tests_proxy_part1
|
||||
- litellm_mapped_tests_proxy_part2
|
||||
- litellm_mapped_tests_llms
|
||||
- litellm_mapped_tests_core
|
||||
- litellm_mapped_tests_mcps
|
||||
- litellm_mapped_tests_integrations
|
||||
- litellm_mapped_tests_litellm_core_utils
|
||||
- litellm_mapped_enterprise_tests
|
||||
|
|
@ -4510,6 +4607,7 @@ workflows:
|
|||
- publish_to_pypi:
|
||||
requires:
|
||||
- mypy_linting
|
||||
- semgrep
|
||||
- local_testing_part1
|
||||
- local_testing_part2
|
||||
- build_and_test
|
||||
|
|
@ -4523,9 +4621,11 @@ workflows:
|
|||
- llm_responses_api_testing
|
||||
- ocr_testing
|
||||
- search_testing
|
||||
- litellm_mapped_tests_proxy
|
||||
- litellm_mapped_tests_proxy_part1
|
||||
- litellm_mapped_tests_proxy_part2
|
||||
- litellm_mapped_tests_llms
|
||||
- litellm_mapped_tests_core
|
||||
- litellm_mapped_tests_mcps
|
||||
- litellm_mapped_tests_integrations
|
||||
- litellm_mapped_tests_litellm_core_utils
|
||||
- litellm_mapped_enterprise_tests
|
||||
|
|
|
|||
|
|
@ -40,38 +40,33 @@ outputs:
|
|||
runs:
|
||||
using: composite
|
||||
steps:
|
||||
- name: Helm | Setup
|
||||
uses: azure/setup-helm@v4
|
||||
with:
|
||||
version: v3.20.0
|
||||
|
||||
- name: Helm | Login
|
||||
shell: bash
|
||||
run: echo ${{ inputs.registry_password }} | helm registry login -u ${{ inputs.registry_username }} --password-stdin ${{ inputs.registry }}
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
|
||||
- name: Helm | Dependency
|
||||
if: inputs.update_dependencies == 'true'
|
||||
shell: bash
|
||||
run: helm dependency update ${{ inputs.path == null && format('{0}/{1}', 'charts', inputs.name) || inputs.path }}
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
- name: Helm | Package
|
||||
shell: bash
|
||||
run: helm package ${{ inputs.path == null && format('{0}/{1}', 'charts', inputs.name) || inputs.path }} --version ${{ inputs.tag }} --app-version ${{ inputs.app_version }}
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
- name: Helm | Push
|
||||
shell: bash
|
||||
run: helm push ${{ inputs.name }}-${{ inputs.tag }}.tgz oci://${{ inputs.registry }}/${{ inputs.repository }}
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
- name: Helm | Logout
|
||||
shell: bash
|
||||
run: helm registry logout ${{ inputs.registry }}
|
||||
env:
|
||||
HELM_EXPERIMENTAL_OCI: '1'
|
||||
|
||||
- name: Helm | Output
|
||||
id: output
|
||||
shell: bash
|
||||
run: echo "image=${{ inputs.registry }}/${{ inputs.repository }}/${{ inputs.name }}:${{ inputs.tag }}" >> $GITHUB_OUTPUT
|
||||
run: echo "image=${{ inputs.registry }}/${{ inputs.repository }}/${{ inputs.name }}:${{ inputs.tag }}" >> $GITHUB_OUTPUT
|
||||
|
|
|
|||
1
.github/pull_request_template.md
vendored
1
.github/pull_request_template.md
vendored
|
|
@ -9,6 +9,7 @@
|
|||
- [ ] I have Added testing in the [`tests/litellm/`](https://github.com/BerriAI/litellm/tree/main/tests/litellm) directory, **Adding at least 1 test is a hard requirement** - [see details](https://docs.litellm.ai/docs/extras/contributing_code)
|
||||
- [ ] My PR passes all unit tests on [`make test-unit`](https://docs.litellm.ai/docs/extras/contributing_code)
|
||||
- [ ] My PR's scope is as isolated as possible, it only solves 1 specific problem
|
||||
- [ ] I have requested a Greptile review by commenting `@greptileai` and received a **Confidence Score of at least 4/5** before requesting a maintainer review
|
||||
|
||||
## CI (LiteLLM team)
|
||||
|
||||
|
|
|
|||
95
.github/workflows/test-litellm-matrix.yml
vendored
Normal file
95
.github/workflows/test-litellm-matrix.yml
vendored
Normal file
|
|
@ -0,0 +1,95 @@
|
|||
name: LiteLLM Unit Tests (Matrix)
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
|
||||
# Cancel in-progress runs for the same PR
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event.pull_request.number || github.ref }}
|
||||
cancel-in-progress: true
|
||||
|
||||
jobs:
|
||||
test:
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 15
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
test-group:
|
||||
# tests/test_litellm split by subdirectory (~560 files total)
|
||||
- name: "llms"
|
||||
path: "tests/test_litellm/llms"
|
||||
workers: 4
|
||||
# tests/test_litellm/proxy split by subdirectory (~180 files total)
|
||||
- name: "proxy-guardrails"
|
||||
path: "tests/test_litellm/proxy/guardrails tests/test_litellm/proxy/management_endpoints tests/test_litellm/proxy/management_helpers"
|
||||
workers: 4
|
||||
- name: "proxy-core"
|
||||
path: "tests/test_litellm/proxy/auth tests/test_litellm/proxy/client tests/test_litellm/proxy/db tests/test_litellm/proxy/hooks tests/test_litellm/proxy/policy_engine"
|
||||
workers: 4
|
||||
- name: "proxy-misc"
|
||||
path: "tests/test_litellm/proxy/_experimental tests/test_litellm/proxy/agent_endpoints tests/test_litellm/proxy/anthropic_endpoints tests/test_litellm/proxy/common_utils tests/test_litellm/proxy/discovery_endpoints tests/test_litellm/proxy/experimental tests/test_litellm/proxy/google_endpoints tests/test_litellm/proxy/health_endpoints tests/test_litellm/proxy/image_endpoints tests/test_litellm/proxy/middleware tests/test_litellm/proxy/openai_files_endpoint tests/test_litellm/proxy/pass_through_endpoints tests/test_litellm/proxy/prompts tests/test_litellm/proxy/public_endpoints tests/test_litellm/proxy/response_api_endpoints tests/test_litellm/proxy/spend_tracking tests/test_litellm/proxy/ui_crud_endpoints tests/test_litellm/proxy/vector_store_endpoints tests/test_litellm/proxy/test_*.py"
|
||||
workers: 4
|
||||
- name: "integrations"
|
||||
path: "tests/test_litellm/integrations"
|
||||
workers: 4
|
||||
- name: "core-utils"
|
||||
path: "tests/test_litellm/litellm_core_utils"
|
||||
workers: 2
|
||||
- name: "other"
|
||||
path: "tests/test_litellm/caching tests/test_litellm/responses tests/test_litellm/secret_managers tests/test_litellm/vector_stores tests/test_litellm/a2a_protocol tests/test_litellm/anthropic_interface tests/test_litellm/completion_extras tests/test_litellm/containers tests/test_litellm/enterprise tests/test_litellm/experimental_mcp_client tests/test_litellm/google_genai tests/test_litellm/images tests/test_litellm/interactions tests/test_litellm/passthrough tests/test_litellm/router_strategy tests/test_litellm/router_utils tests/test_litellm/types"
|
||||
workers: 4
|
||||
- name: "root"
|
||||
path: "tests/test_litellm/test_*.py"
|
||||
workers: 4
|
||||
# tests/proxy_unit_tests split alphabetically (~48 files total)
|
||||
- name: "proxy-unit-a"
|
||||
path: "tests/proxy_unit_tests/test_[a-o]*.py"
|
||||
workers: 2
|
||||
- name: "proxy-unit-b"
|
||||
path: "tests/proxy_unit_tests/test_[p-z]*.py"
|
||||
workers: 2
|
||||
|
||||
name: test (${{ matrix.test-group.name }})
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v4
|
||||
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: "3.12"
|
||||
|
||||
- name: Install Poetry
|
||||
uses: snok/install-poetry@v1
|
||||
|
||||
- name: Cache Poetry dependencies
|
||||
uses: actions/cache@v4
|
||||
with:
|
||||
path: |
|
||||
~/.cache/pypoetry
|
||||
~/.cache/pip
|
||||
.venv
|
||||
key: ${{ runner.os }}-poetry-${{ hashFiles('poetry.lock') }}
|
||||
restore-keys: |
|
||||
${{ runner.os }}-poetry-
|
||||
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
poetry config virtualenvs.in-project true
|
||||
poetry install --with dev,proxy-dev --extras "proxy semantic-router"
|
||||
poetry run pip install pytest-retry==1.6.3 pytest-xdist google-genai==1.22.0 \
|
||||
google-cloud-aiplatform>=1.38 fastapi-offline==1.7.3 python-multipart==0.0.22 openapi-core
|
||||
|
||||
- name: Setup litellm-enterprise
|
||||
run: |
|
||||
cd enterprise && poetry run pip install -e . && cd ..
|
||||
|
||||
- name: Run tests - ${{ matrix.test-group.name }}
|
||||
run: |
|
||||
poetry run pytest ${{ matrix.test-group.path }} \
|
||||
--tb=short -vv \
|
||||
--maxfail=10 \
|
||||
-n ${{ matrix.test-group.workers }} \
|
||||
--durations=20
|
||||
32
.github/workflows/test-litellm-ui-build.yml
vendored
Normal file
32
.github/workflows/test-litellm-ui-build.yml
vendored
Normal file
|
|
@ -0,0 +1,32 @@
|
|||
name: UI Build Check
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main]
|
||||
|
||||
jobs:
|
||||
build-ui:
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 10
|
||||
defaults:
|
||||
run:
|
||||
working-directory: ui/litellm-dashboard
|
||||
|
||||
steps:
|
||||
- name: Checkout repository
|
||||
uses: actions/checkout@v4
|
||||
|
||||
- name: Setup Node.js
|
||||
uses: actions/setup-node@v4
|
||||
with:
|
||||
node-version: "20"
|
||||
cache: "npm"
|
||||
cache-dependency-path: ui/litellm-dashboard/package-lock.json
|
||||
|
||||
- name: Install dependencies
|
||||
run: npm install
|
||||
|
||||
- name: Build
|
||||
run: npm run build
|
||||
8
.github/workflows/test-litellm.yml
vendored
8
.github/workflows/test-litellm.yml
vendored
|
|
@ -1,8 +1,12 @@
|
|||
name: LiteLLM Mock Tests (folder - tests/test_litellm)
|
||||
|
||||
# DEPRECATED: This workflow is replaced by test-litellm-matrix.yml which runs
|
||||
# the same tests in parallel across 10 jobs for faster CI times.
|
||||
# Kept for manual debugging only.
|
||||
on:
|
||||
pull_request:
|
||||
branches: [ main ]
|
||||
workflow_dispatch: # Manual trigger only
|
||||
# pull_request:
|
||||
# branches: [ main ]
|
||||
|
||||
jobs:
|
||||
test:
|
||||
|
|
|
|||
1
.gitignore
vendored
1
.gitignore
vendored
|
|
@ -2,6 +2,7 @@
|
|||
.venv
|
||||
.venv_policy_test
|
||||
.env
|
||||
.claude
|
||||
.newenv
|
||||
newenv/*
|
||||
litellm/proxy/myenv/*
|
||||
|
|
|
|||
22
.semgrep/rules/README.md
Normal file
22
.semgrep/rules/README.md
Normal file
|
|
@ -0,0 +1,22 @@
|
|||
# Custom Semgrep rules for LiteLLM
|
||||
|
||||
Add custom rule YAML files here. Semgrep loads all `.yml`/`.yaml` files under this directory.
|
||||
|
||||
**Run only custom rules (CI / fail on findings):**
|
||||
|
||||
```bash
|
||||
semgrep scan --config .semgrep/rules . --error
|
||||
```
|
||||
|
||||
**Run with registry + custom rules:**
|
||||
|
||||
```bash
|
||||
semgrep scan --config auto --config .semgrep/rules .
|
||||
```
|
||||
|
||||
**Layout:**
|
||||
|
||||
- `python/` – Python-specific rules (security, patterns)
|
||||
- Add more subdirs as needed (e.g. `generic/` for language-agnostic rules)
|
||||
|
||||
See [Semgrep rule syntax](https://semgrep.dev/docs/writing-rules/rule-syntax/).
|
||||
17
.semgrep/rules/python/reliability/unbounded-memory.yml
Normal file
17
.semgrep/rules/python/reliability/unbounded-memory.yml
Normal file
|
|
@ -0,0 +1,17 @@
|
|||
# Unbounded memory growth – data structures without a clear max limit
|
||||
# Can lead to OOM under load.
|
||||
|
||||
rules:
|
||||
- id: unbounded-asyncio-queue
|
||||
message: asyncio.Queue() with no maxsize can grow unbounded. Use asyncio.Queue(maxsize=N) for integrations (e.g. log queues).
|
||||
severity: ERROR
|
||||
languages: [python]
|
||||
pattern-either:
|
||||
- pattern: asyncio.Queue()
|
||||
- pattern: asyncio.Queue(maxsize=0)
|
||||
metadata:
|
||||
category: reliability
|
||||
cwe: "CWE-400: Uncontrolled Resource Consumption"
|
||||
tags: [python, reliability]
|
||||
confidence: HIGH
|
||||
source: https://docs.python.org/3/library/asyncio-queue.html
|
||||
14
.semgrep/rules/python/unbounded-memory.yml
Normal file
14
.semgrep/rules/python/unbounded-memory.yml
Normal file
|
|
@ -0,0 +1,14 @@
|
|||
# Unbounded memory growth – data structures without a clear max limit
|
||||
# Can lead to OOM under load.
|
||||
|
||||
rules:
|
||||
- id: unbounded-asyncio-queue
|
||||
message: asyncio.Queue() with no maxsize can grow unbounded. Use asyncio.Queue(maxsize=N) for integrations (e.g. log queues).
|
||||
severity: ERROR
|
||||
languages: [python]
|
||||
pattern-either:
|
||||
- pattern: asyncio.Queue()
|
||||
- pattern: asyncio.Queue(maxsize=0)
|
||||
metadata:
|
||||
category: correctness
|
||||
cwe: "CWE-400: Uncontrolled Resource Consumption"
|
||||
46
Makefile
46
Makefile
|
|
@ -1,7 +1,9 @@
|
|||
# LiteLLM Makefile
|
||||
# Simple Makefile for running tests and basic development tasks
|
||||
|
||||
.PHONY: help test test-unit test-integration test-unit-helm \
|
||||
.PHONY: help test test-unit test-unit-llms test-unit-proxy-guardrails test-unit-proxy-core test-unit-proxy-misc \
|
||||
test-unit-integrations test-unit-core-utils test-unit-other test-unit-root \
|
||||
test-proxy-unit-a test-proxy-unit-b test-integration test-unit-helm \
|
||||
info lint lint-dev format \
|
||||
install-dev install-proxy-dev install-test-deps \
|
||||
install-helm-unittest check-circular-imports check-import-safety
|
||||
|
|
@ -25,6 +27,16 @@ help:
|
|||
@echo " make check-import-safety - Check import safety"
|
||||
@echo " make test - Run all tests"
|
||||
@echo " make test-unit - Run unit tests (tests/test_litellm)"
|
||||
@echo " make test-unit-llms - Run LLM provider tests (~225 files)"
|
||||
@echo " make test-unit-proxy-guardrails - Run proxy guardrails+mgmt tests (~51 files)"
|
||||
@echo " make test-unit-proxy-core - Run proxy auth+client+db+hooks tests (~52 files)"
|
||||
@echo " make test-unit-proxy-misc - Run proxy misc tests (~77 files)"
|
||||
@echo " make test-unit-integrations - Run integration tests (~60 files)"
|
||||
@echo " make test-unit-core-utils - Run core utils tests (~32 files)"
|
||||
@echo " make test-unit-other - Run other tests (caching, responses, etc., ~69 files)"
|
||||
@echo " make test-unit-root - Run root-level tests (~34 files)"
|
||||
@echo " make test-proxy-unit-a - Run proxy_unit_tests (a-o, ~20 files)"
|
||||
@echo " make test-proxy-unit-b - Run proxy_unit_tests (p-z, ~28 files)"
|
||||
@echo " make test-integration - Run integration tests"
|
||||
@echo " make test-unit-helm - Run helm unit tests"
|
||||
|
||||
|
|
@ -129,6 +141,38 @@ test:
|
|||
test-unit: install-test-deps
|
||||
poetry run pytest tests/test_litellm -x -vv -n 4
|
||||
|
||||
# Matrix test targets (matching CI workflow groups)
|
||||
test-unit-llms: install-test-deps
|
||||
poetry run pytest tests/test_litellm/llms --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-proxy-guardrails: install-test-deps
|
||||
poetry run pytest tests/test_litellm/proxy/guardrails tests/test_litellm/proxy/management_endpoints tests/test_litellm/proxy/management_helpers --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-proxy-core: install-test-deps
|
||||
poetry run pytest tests/test_litellm/proxy/auth tests/test_litellm/proxy/client tests/test_litellm/proxy/db tests/test_litellm/proxy/hooks tests/test_litellm/proxy/policy_engine --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-proxy-misc: install-test-deps
|
||||
poetry run pytest tests/test_litellm/proxy/_experimental tests/test_litellm/proxy/agent_endpoints tests/test_litellm/proxy/anthropic_endpoints tests/test_litellm/proxy/common_utils tests/test_litellm/proxy/discovery_endpoints tests/test_litellm/proxy/experimental tests/test_litellm/proxy/google_endpoints tests/test_litellm/proxy/health_endpoints tests/test_litellm/proxy/image_endpoints tests/test_litellm/proxy/middleware tests/test_litellm/proxy/openai_files_endpoint tests/test_litellm/proxy/pass_through_endpoints tests/test_litellm/proxy/prompts tests/test_litellm/proxy/public_endpoints tests/test_litellm/proxy/response_api_endpoints tests/test_litellm/proxy/spend_tracking tests/test_litellm/proxy/ui_crud_endpoints tests/test_litellm/proxy/vector_store_endpoints tests/test_litellm/proxy/test_*.py --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-integrations: install-test-deps
|
||||
poetry run pytest tests/test_litellm/integrations --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-core-utils: install-test-deps
|
||||
poetry run pytest tests/test_litellm/litellm_core_utils --tb=short -vv -n 2 --durations=20
|
||||
|
||||
test-unit-other: install-test-deps
|
||||
poetry run pytest tests/test_litellm/caching tests/test_litellm/responses tests/test_litellm/secret_managers tests/test_litellm/vector_stores tests/test_litellm/a2a_protocol tests/test_litellm/anthropic_interface tests/test_litellm/completion_extras tests/test_litellm/containers tests/test_litellm/enterprise tests/test_litellm/experimental_mcp_client tests/test_litellm/google_genai tests/test_litellm/images tests/test_litellm/interactions tests/test_litellm/passthrough tests/test_litellm/router_strategy tests/test_litellm/router_utils tests/test_litellm/types --tb=short -vv -n 4 --durations=20
|
||||
|
||||
test-unit-root: install-test-deps
|
||||
poetry run pytest tests/test_litellm/test_*.py --tb=short -vv -n 4 --durations=20
|
||||
|
||||
# Proxy unit tests (tests/proxy_unit_tests split alphabetically)
|
||||
test-proxy-unit-a: install-test-deps
|
||||
poetry run pytest tests/proxy_unit_tests/test_[a-o]*.py --tb=short -vv -n 2 --durations=20
|
||||
|
||||
test-proxy-unit-b: install-test-deps
|
||||
poetry run pytest tests/proxy_unit_tests/test_[p-z]*.py --tb=short -vv -n 2 --durations=20
|
||||
|
||||
test-integration:
|
||||
poetry run pytest tests/ -k "not test_litellm"
|
||||
|
||||
|
|
|
|||
|
|
@ -16,10 +16,14 @@ Usage:
|
|||
import asyncio
|
||||
import base64
|
||||
import json
|
||||
import os
|
||||
import pyaudio
|
||||
import websockets
|
||||
from typing import Optional
|
||||
|
||||
# Bounded queue size for audio chunks (configurable via env to avoid unbounded memory)
|
||||
AUDIO_QUEUE_MAXSIZE = int(os.getenv("LITELLM_ASYNCIO_QUEUE_MAXSIZE", 10_000))
|
||||
|
||||
# Audio configuration (matching Nova Sonic requirements)
|
||||
INPUT_SAMPLE_RATE = 16000 # Nova Sonic expects 16kHz input
|
||||
OUTPUT_SAMPLE_RATE = 24000 # Nova Sonic outputs 24kHz
|
||||
|
|
@ -40,7 +44,7 @@ class RealtimeClient:
|
|||
self.api_key = api_key
|
||||
self.ws: Optional[websockets.WebSocketClientProtocol] = None
|
||||
self.is_active = False
|
||||
self.audio_queue = asyncio.Queue()
|
||||
self.audio_queue = asyncio.Queue(maxsize=AUDIO_QUEUE_MAXSIZE)
|
||||
self.pyaudio = pyaudio.PyAudio()
|
||||
self.input_stream = None
|
||||
self.output_stream = None
|
||||
|
|
|
|||
|
|
@ -26,6 +26,10 @@ version: 1.1.0
|
|||
# It is recommended to use it with quotes.
|
||||
appVersion: v1.80.12
|
||||
|
||||
annotations:
|
||||
org.opencontainers.image.source: "https://github.com/BerriAI/litellm"
|
||||
org.opencontainers.image.url: "https://docs.litellm.ai/"
|
||||
|
||||
dependencies:
|
||||
- name: "postgresql"
|
||||
version: ">=13.3.0"
|
||||
|
|
|
|||
|
|
@ -59,7 +59,8 @@ RUN mkdir -p /var/lib/litellm/ui && \
|
|||
mkdir -p "$folder_name" && \
|
||||
mv "$html_file" "$folder_name/index.html"; \
|
||||
fi; \
|
||||
done ) && \
|
||||
done && \
|
||||
touch .litellm_ui_ready ) && \
|
||||
cd /app/ui/litellm-dashboard && rm -rf ./out
|
||||
|
||||
# Build litellm wheel and place it in wheels dir (replace any PyPI wheels)
|
||||
|
|
|
|||
|
|
@ -70,9 +70,12 @@ docker compose -f docker-compose.yml -f docker-compose.hardened.yml up -d
|
|||
|
||||
This setup:
|
||||
- Builds from `docker/Dockerfile.non_root` with Prisma engines and Node toolchain baked into the image.
|
||||
- Runs the proxy as a non-root user with a read-only rootfs and only two writable tmpfs mounts:
|
||||
- Runs the proxy as a non-root user with a read-only rootfs and only writable tmpfs mounts:
|
||||
- `/app/cache` (Prisma/NPM cache; backing `PRISMA_BINARY_CACHE_DIR`, `NPM_CONFIG_CACHE`, `XDG_CACHE_HOME`)
|
||||
- `/app/migrations` (Prisma migration workspace; backing `LITELLM_MIGRATION_DIR`)
|
||||
- Pre-builds and serves the admin UI from read-only paths:
|
||||
- `/var/lib/litellm/ui` (pre-restructured Next.js UI with `.litellm_ui_ready` marker)
|
||||
- `/var/lib/litellm/assets` (UI logos and assets)
|
||||
- Routes all outbound traffic through a local Squid proxy that denies egress, so Prisma migrations must use the cached CLI and engines.
|
||||
|
||||
You should also verify offline Prisma behaviour with:
|
||||
|
|
|
|||
274
docs/my-website/blog/claude_code_beta_headers/index.md
Normal file
274
docs/my-website/blog/claude_code_beta_headers/index.md
Normal file
|
|
@ -0,0 +1,274 @@
|
|||
---
|
||||
slug: claude_code_beta_headers
|
||||
title: "Claude Code - Managing Anthropic Beta Headers"
|
||||
date: 2026-02-16T10:00:00
|
||||
authors:
|
||||
- name: Sameer Kankute
|
||||
title: SWE @ LiteLLM (LLM Translation)
|
||||
url: https://www.linkedin.com/in/sameer-kankute/
|
||||
image_url: https://pbs.twimg.com/profile_images/2001352686994907136/ONgNuSk5_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
- name: Krrish Dholakia
|
||||
title: "CEO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
description: "How to manage and configure Anthropic beta headers with Claude Code in LiteLLM: filtering, mapping, and dynamic updates across providers."
|
||||
tags: [anthropic, claude, beta headers, configuration, liteLLM]
|
||||
hide_table_of_contents: false
|
||||
|
||||
---
|
||||
import Image from '@theme/IdealImage';
|
||||
|
||||
When using Claude Code with LiteLLM and non-Anthropic providers (Bedrock, Azure AI, Vertex AI), you need to ensure that only supported beta headers are sent to each provider. This guide explains how to add support for new beta headers or fix invalid beta header errors.
|
||||
|
||||
## What Are Beta Headers?
|
||||
|
||||
Anthropic uses beta headers to enable experimental features in Claude. When you use Claude Code, it may send beta headers like:
|
||||
|
||||
```
|
||||
anthropic-beta: prompt-caching-scope-2026-01-05,advanced-tool-use-2025-11-20
|
||||
```
|
||||
|
||||
However, not all providers support all Anthropic beta features. LiteLLM uses `anthropic_beta_headers_config.json` to manage which beta headers are supported by each provider.
|
||||
|
||||
## Common Error Message
|
||||
|
||||
```bash
|
||||
Error: The model returned the following errors: invalid beta flag
|
||||
```
|
||||
|
||||
## How LiteLLM Handles Beta Headers
|
||||
|
||||
LiteLLM uses a strict validation approach with a configuration file:
|
||||
|
||||
```
|
||||
litellm/litellm/anthropic_beta_headers_config.json
|
||||
```
|
||||
|
||||
This JSON file contains a **mapping** of beta headers for each provider:
|
||||
- **Keys**: Input beta header names (from Anthropic)
|
||||
- **Values**: Provider-specific header names (or `null` if unsupported)
|
||||
- **Validation**: Only headers present in the mapping with non-null values are forwarded
|
||||
|
||||
This enforces stricter validation than just filtering unsupported headers - headers must be explicitly defined to be allowed.
|
||||
|
||||
## Adding Support for a New Beta Header
|
||||
|
||||
When Anthropic releases a new beta feature, you need to add it to the configuration file for each provider.
|
||||
|
||||
### Step 1: Add the New Beta Header
|
||||
|
||||
Open `anthropic_beta_headers_config.json` and add the new header to each provider's mapping:
|
||||
|
||||
```json title="anthropic_beta_headers_config.json"
|
||||
{
|
||||
"description": "Mapping of Anthropic beta headers for each provider. Keys are input header names, values are provider-specific header names (or null if unsupported). Only headers present in mapping keys with non-null values can be forwarded.",
|
||||
"anthropic": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"new-feature-2026-03-01": "new-feature-2026-03-01",
|
||||
...
|
||||
},
|
||||
"azure_ai": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"new-feature-2026-03-01": "new-feature-2026-03-01",
|
||||
...
|
||||
},
|
||||
"bedrock_converse": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"new-feature-2026-03-01": null,
|
||||
...
|
||||
},
|
||||
"bedrock": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"new-feature-2026-03-01": null,
|
||||
...
|
||||
},
|
||||
"vertex_ai": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"new-feature-2026-03-01": null,
|
||||
...
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Key Points:**
|
||||
- **Supported headers**: Set the value to the provider-specific header name (often the same as the key)
|
||||
- **Unsupported headers**: Set the value to `null`
|
||||
- **Header transformations**: Some providers use different header names (e.g., Bedrock maps `advanced-tool-use-2025-11-20` to `tool-search-tool-2025-10-19`)
|
||||
- **Alphabetical order**: Keep headers sorted alphabetically for maintainability
|
||||
|
||||
### Step 2: Reload Configuration (No Restart Required!)
|
||||
|
||||
**Option 1: Dynamic Reload Without Restart**
|
||||
|
||||
Instead of restarting your application, you can dynamically reload the beta headers configuration using environment variables and API endpoints:
|
||||
|
||||
```bash
|
||||
# Set environment variable to fetch from remote URL (Do this if you want to point it to some other URL)
|
||||
export LITELLM_ANTHROPIC_BETA_HEADERS_URL="https://raw.githubusercontent.com/BerriAI/litellm/main/litellm/anthropic_beta_headers_config.json"
|
||||
|
||||
# Manually trigger reload via API (no restart needed!)
|
||||
curl -X POST "https://your-proxy-url/reload/anthropic_beta_headers" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
**Option 2: Schedule Automatic Reloads**
|
||||
|
||||
Set up automatic reloading to always stay up-to-date with the latest beta headers:
|
||||
|
||||
```bash
|
||||
# Reload configuration every 24 hours
|
||||
curl -X POST "https://your-proxy-url/schedule/anthropic_beta_headers_reload?hours=24" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
**Option 3: Traditional Restart**
|
||||
|
||||
If you prefer the traditional approach, restart your LiteLLM proxy or application:
|
||||
|
||||
```bash
|
||||
# If using LiteLLM proxy
|
||||
litellm --config config.yaml
|
||||
|
||||
# If using Python SDK
|
||||
# Just restart your Python application
|
||||
```
|
||||
|
||||
:::tip Zero-Downtime Updates
|
||||
With dynamic reloading, you can fix invalid beta header errors **without restarting your service**! This is especially useful in production environments where downtime is costly.
|
||||
|
||||
See [Auto Sync Anthropic Beta Headers](../proxy/sync_anthropic_beta_headers.md) for complete documentation.
|
||||
:::
|
||||
|
||||
## Fixing Invalid Beta Header Errors
|
||||
|
||||
If you encounter an "invalid beta flag" error, it means a beta header is being sent that the provider doesn't support.
|
||||
|
||||
### Step 1: Identify the Problematic Header
|
||||
|
||||
Check your logs to see which header is causing the issue:
|
||||
|
||||
```bash
|
||||
Error: The model returned the following errors: invalid beta flag: new-feature-2026-03-01
|
||||
```
|
||||
|
||||
### Step 2: Update the Config
|
||||
|
||||
Set the header value to `null` for that provider:
|
||||
|
||||
```json title="anthropic_beta_headers_config.json"
|
||||
{
|
||||
"bedrock_converse": {
|
||||
"new-feature-2026-03-01": null
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Step 3: Restart and Test
|
||||
|
||||
Restart your application and verify the header is now filtered out.
|
||||
|
||||
## Contributing a Fix to LiteLLM
|
||||
|
||||
Help the community by contributing your fix!
|
||||
|
||||
### What to Include in Your PR
|
||||
|
||||
1. **Update the config file**: Add the new beta header to `litellm/anthropic_beta_headers_config.json`
|
||||
2. **Test your changes**: Verify the header is correctly filtered/mapped for each provider
|
||||
3. **Documentation**: Include provider documentation links showing which headers are supported
|
||||
|
||||
### Example PR Description
|
||||
|
||||
```markdown
|
||||
## Add support for new-feature-2026-03-01 beta header
|
||||
|
||||
### Changes
|
||||
- Added `new-feature-2026-03-01` to anthropic_beta_headers_config.json
|
||||
- Set to `null` for bedrock_converse (unsupported)
|
||||
- Set to header name for anthropic, azure_ai (supported)
|
||||
|
||||
### Testing
|
||||
Tested with:
|
||||
- ✅ Anthropic: Header passed through correctly
|
||||
- ✅ Azure AI: Header passed through correctly
|
||||
- ✅ Bedrock Converse: Header filtered out (returns error without fix)
|
||||
|
||||
### References
|
||||
- Anthropic docs: [link]
|
||||
- AWS Bedrock docs: [link]
|
||||
```
|
||||
|
||||
|
||||
## How Beta Header Filtering Works
|
||||
|
||||
When you make a request through LiteLLM:
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant CC as Claude Code
|
||||
participant LP as LiteLLM
|
||||
participant Config as Beta Headers Config
|
||||
participant Provider as Provider (Bedrock/Azure/etc)
|
||||
|
||||
CC->>LP: Request with beta headers
|
||||
Note over CC,LP: anthropic-beta: header1,header2,header3
|
||||
|
||||
LP->>Config: Load header mapping for provider
|
||||
Config-->>LP: Returns mapping (header→value or null)
|
||||
|
||||
Note over LP: Validate & Transform:<br/>1. Check if header exists in mapping<br/>2. Filter out null values<br/>3. Map to provider-specific names
|
||||
|
||||
LP->>Provider: Request with filtered & mapped headers
|
||||
Note over LP,Provider: anthropic-beta: mapped-header2<br/>(header1, header3 filtered out)
|
||||
|
||||
Provider-->>LP: Success response
|
||||
LP-->>CC: Response
|
||||
```
|
||||
|
||||
### Filtering Rules
|
||||
|
||||
1. **Header must exist in mapping**: Unknown headers are filtered out
|
||||
2. **Header must have non-null value**: Headers with `null` values are filtered out
|
||||
3. **Header transformation**: Headers are mapped to provider-specific names (e.g., `advanced-tool-use-2025-11-20` → `tool-search-tool-2025-10-19` for Bedrock)
|
||||
|
||||
### Example
|
||||
|
||||
Request with headers:
|
||||
```
|
||||
anthropic-beta: advanced-tool-use-2025-11-20,computer-use-2025-01-24,unknown-header
|
||||
```
|
||||
|
||||
For Bedrock Converse:
|
||||
- ✅ `computer-use-2025-01-24` → `computer-use-2025-01-24` (supported, passed through)
|
||||
- ❌ `advanced-tool-use-2025-11-20` → filtered out (null value in config)
|
||||
- ❌ `unknown-header` → filtered out (not in config)
|
||||
|
||||
Result sent to Bedrock:
|
||||
```
|
||||
anthropic-beta: computer-use-2025-01-24
|
||||
```
|
||||
|
||||
## Dynamic Configuration Management (No Restart Required!)
|
||||
|
||||
### Environment Variables
|
||||
|
||||
Control how LiteLLM loads the beta headers configuration:
|
||||
|
||||
| Variable | Description | Default |
|
||||
|----------|-------------|---------|
|
||||
| `LITELLM_ANTHROPIC_BETA_HEADERS_URL` | URL to fetch config from | GitHub main branch |
|
||||
| `LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS` | Set to `True` to use local config only | `False` |
|
||||
|
||||
**Example: Use Custom Config URL**
|
||||
```bash
|
||||
export LITELLM_ANTHROPIC_BETA_HEADERS_URL="https://your-company.com/custom-beta-headers.json"
|
||||
```
|
||||
|
||||
**Example: Use Local Config Only (No Remote Fetching)**
|
||||
```bash
|
||||
export LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS=True
|
||||
```
|
||||
|
|
@ -185,7 +185,7 @@ curl --location 'http://0.0.0.0:4000/chat/completions' \
|
|||
model_list:
|
||||
- model_name: claude-opus-4-6
|
||||
litellm_params:
|
||||
model: bedrock/anthropic.claude-opus-4-6-v1:0
|
||||
model: bedrock/anthropic.claude-opus-4-6-v1
|
||||
aws_access_key_id: os.environ/AWS_ACCESS_KEY_ID
|
||||
aws_secret_access_key: os.environ/AWS_SECRET_ACCESS_KEY
|
||||
aws_region_name: us-east-1
|
||||
|
|
@ -389,6 +389,10 @@ Compaction blocks are also supported in streaming mode. You'll receive:
|
|||
|
||||
### Adaptive Thinking
|
||||
|
||||
:::note
|
||||
When using `reasoning_effort` with Claude Opus 4.6, all values (`low`, `medium`, `high`) are mapped to `thinking: {type: "adaptive"}`. To use explicit thinking budgets with `type: "enabled"`, pass the native `thinking` parameter directly (see "Native thinking param" tab below).
|
||||
:::
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="completions" label="/chat/completions">
|
||||
|
||||
|
|
@ -434,6 +438,21 @@ curl --location 'http://0.0.0.0:4000/v1/messages' \
|
|||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="native" label="Native thinking param">
|
||||
|
||||
Use the `thinking` parameter directly for adaptive thinking via the SDK:
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-opus-4-6",
|
||||
messages=[{"role": "user", "content": "Solve this complex problem: What is the optimal strategy for..."}],
|
||||
thinking={"type": "adaptive"},
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
|
|
|||
394
docs/my-website/blog/minimax_m2_5/index.md
Normal file
394
docs/my-website/blog/minimax_m2_5/index.md
Normal file
|
|
@ -0,0 +1,394 @@
|
|||
---
|
||||
slug: minimax_m2_5
|
||||
title: "Day 0 Support: MiniMax-M2.5"
|
||||
date: 2026-02-12T10:00:00
|
||||
authors:
|
||||
- name: Sameer Kankute
|
||||
title: SWE @ LiteLLM (LLM Translation)
|
||||
url: https://www.linkedin.com/in/sameer-kankute/
|
||||
image_url: https://pbs.twimg.com/profile_images/2001352686994907136/ONgNuSk5_400x400.jpg
|
||||
- name: Krrish Dholakia
|
||||
title: "CEO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
description: "Day 0 support for MiniMax-M2.5 on LiteLLM"
|
||||
tags: [minimax, M2.5, llm]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
LiteLLM now supports MiniMax-M2.5 on Day 0. Use it across OpenAI-compatible and Anthropic-compatible APIs through the LiteLLM AI Gateway.
|
||||
|
||||
## Supported Models
|
||||
|
||||
LiteLLM supports the following MiniMax models:
|
||||
|
||||
| Model | Description | Input Cost | Output Cost | Context Window |
|
||||
|-------|-------------|------------|-------------|----------------|
|
||||
| **MiniMax-M2.5** | Advanced reasoning, Agentic capabilities | $0.3/M tokens | $1.2/M tokens | 1M tokens |
|
||||
| **MiniMax-M2.5-lightning** | Faster and More Agile (~100 tps) | $0.3/M tokens | $2.4/M tokens | 1M tokens |
|
||||
|
||||
## Features Supported
|
||||
|
||||
- **Prompt Caching**: Reduce costs with cached prompts ($0.03/M tokens for cache read, $0.375/M tokens for cache write)
|
||||
- **Function Calling**: Built-in tool calling support
|
||||
- **Reasoning**: Advanced reasoning capabilities with thinking support
|
||||
- **System Messages**: Full system message support
|
||||
- **Cost Tracking**: Automatic cost calculation for all requests
|
||||
|
||||
## Docker Image
|
||||
|
||||
```bash
|
||||
docker pull litellm/litellm:v1.81.3-stable
|
||||
```
|
||||
|
||||
## Usage - OpenAI Compatible API (/v1/chat/completions)
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: minimax-m2-5
|
||||
litellm_params:
|
||||
model: minimax/MiniMax-M2.5
|
||||
api_key: os.environ/MINIMAX_API_KEY
|
||||
api_base: https://api.minimax.io/v1
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e MINIMAX_API_KEY=$MINIMAX_API_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:v1.81.3-stable \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "minimax-m2-5",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### With Reasoning Split
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "minimax-m2-5",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Solve: 2+2=?"
|
||||
}
|
||||
],
|
||||
"extra_body": {
|
||||
"reasoning_split": true
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
## Usage - Anthropic Compatible API (/v1/messages)
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="LiteLLM Proxy">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: minimax-m2-5
|
||||
litellm_params:
|
||||
model: minimax/MiniMax-M2.5
|
||||
api_key: os.environ/MINIMAX_API_KEY
|
||||
api_base: https://api.minimax.io/anthropic/v1/messages
|
||||
```
|
||||
|
||||
**2. Start the proxy**
|
||||
|
||||
```bash
|
||||
docker run -d \
|
||||
-p 4000:4000 \
|
||||
-e MINIMAX_API_KEY=$MINIMAX_API_KEY \
|
||||
-v $(pwd)/config.yaml:/app/config.yaml \
|
||||
ghcr.io/berriai/litellm:v1.81.3-stable \
|
||||
--config /app/config.yaml
|
||||
```
|
||||
|
||||
**3. Test it!**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "minimax-m2-5",
|
||||
"max_tokens": 1000,
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### With Thinking
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/v1/messages' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer $LITELLM_KEY' \
|
||||
--data '{
|
||||
"model": "minimax-m2-5",
|
||||
"max_tokens": 1000,
|
||||
"thinking": {
|
||||
"type": "enabled",
|
||||
"budget_tokens": 1000
|
||||
},
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Solve: 2+2=?"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
## Usage - LiteLLM SDK
|
||||
|
||||
### OpenAI-compatible API
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.completion(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[
|
||||
{"role": "user", "content": "Hello, how are you?"}
|
||||
],
|
||||
api_key="your-minimax-api-key",
|
||||
api_base="https://api.minimax.io/v1"
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
### Anthropic-compatible API
|
||||
|
||||
```python
|
||||
import litellm
|
||||
|
||||
response = litellm.anthropic.messages.acreate(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[{"role": "user", "content": "Hello, how are you?"}],
|
||||
api_key="your-minimax-api-key",
|
||||
api_base="https://api.minimax.io/anthropic/v1/messages",
|
||||
max_tokens=1000
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
### With Thinking
|
||||
|
||||
```python
|
||||
response = litellm.anthropic.messages.acreate(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[{"role": "user", "content": "Solve: 2+2=?"}],
|
||||
thinking={"type": "enabled", "budget_tokens": 1000},
|
||||
api_key="your-minimax-api-key"
|
||||
)
|
||||
|
||||
# Access thinking content
|
||||
for block in response.choices[0].message.content:
|
||||
if hasattr(block, 'type') and block.type == 'thinking':
|
||||
print(f"Thinking: {block.thinking}")
|
||||
```
|
||||
|
||||
### With Reasoning Split (OpenAI API)
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[
|
||||
{"role": "user", "content": "Solve: 2+2=?"}
|
||||
],
|
||||
extra_body={"reasoning_split": True},
|
||||
api_key="your-minimax-api-key",
|
||||
api_base="https://api.minimax.io/v1"
|
||||
)
|
||||
|
||||
# Access thinking and response
|
||||
if hasattr(response.choices[0].message, 'reasoning_details'):
|
||||
print(f"Thinking: {response.choices[0].message.reasoning_details}")
|
||||
print(f"Response: {response.choices[0].message.content}")
|
||||
```
|
||||
|
||||
## Cost Tracking
|
||||
|
||||
LiteLLM automatically tracks costs for MiniMax-M2.5 requests. The pricing is:
|
||||
|
||||
- **Input**: $0.3 per 1M tokens
|
||||
- **Output**: $1.2 per 1M tokens
|
||||
- **Cache Read**: $0.03 per 1M tokens
|
||||
- **Cache Write**: $0.375 per 1M tokens
|
||||
|
||||
### Accessing Cost Information
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[{"role": "user", "content": "Hello!"}],
|
||||
api_key="your-minimax-api-key"
|
||||
)
|
||||
|
||||
# Access cost information
|
||||
print(f"Cost: ${response._hidden_params.get('response_cost', 0)}")
|
||||
```
|
||||
|
||||
## Streaming Support
|
||||
|
||||
### OpenAI API
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[{"role": "user", "content": "Tell me a story"}],
|
||||
stream=True,
|
||||
api_key="your-minimax-api-key",
|
||||
api_base="https://api.minimax.io/v1"
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
if chunk.choices[0].delta.content:
|
||||
print(chunk.choices[0].delta.content, end="")
|
||||
```
|
||||
|
||||
### Streaming with Reasoning Split
|
||||
|
||||
```python
|
||||
stream = litellm.completion(
|
||||
model="minimax/MiniMax-M2.5",
|
||||
messages=[
|
||||
{"role": "user", "content": "Tell me a story"},
|
||||
],
|
||||
extra_body={"reasoning_split": True},
|
||||
stream=True,
|
||||
api_key="your-minimax-api-key",
|
||||
api_base="https://api.minimax.io/v1"
|
||||
)
|
||||
|
||||
reasoning_buffer = ""
|
||||
text_buffer = ""
|
||||
|
||||
for chunk in stream:
|
||||
if hasattr(chunk.choices[0].delta, "reasoning_details") and chunk.choices[0].delta.reasoning_details:
|
||||
for detail in chunk.choices[0].delta.reasoning_details:
|
||||
if "text" in detail:
|
||||
reasoning_text = detail["text"]
|
||||
new_reasoning = reasoning_text[len(reasoning_buffer):]
|
||||
if new_reasoning:
|
||||
print(new_reasoning, end="", flush=True)
|
||||
reasoning_buffer = reasoning_text
|
||||
|
||||
if chunk.choices[0].delta.content:
|
||||
content_text = chunk.choices[0].delta.content
|
||||
new_text = content_text[len(text_buffer):] if text_buffer else content_text
|
||||
if new_text:
|
||||
print(new_text, end="", flush=True)
|
||||
text_buffer = content_text
|
||||
```
|
||||
|
||||
## Using with Native SDKs
|
||||
|
||||
### Anthropic SDK via LiteLLM Proxy
|
||||
|
||||
```python
|
||||
import os
|
||||
os.environ["ANTHROPIC_BASE_URL"] = "http://localhost:4000"
|
||||
os.environ["ANTHROPIC_API_KEY"] = "sk-1234" # Your LiteLLM proxy key
|
||||
|
||||
import anthropic
|
||||
|
||||
client = anthropic.Anthropic()
|
||||
|
||||
message = client.messages.create(
|
||||
model="minimax-m2-5",
|
||||
max_tokens=1000,
|
||||
system="You are a helpful assistant.",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "text",
|
||||
"text": "Hi, how are you?"
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
)
|
||||
|
||||
for block in message.content:
|
||||
if block.type == "thinking":
|
||||
print(f"Thinking:\n{block.thinking}\n")
|
||||
elif block.type == "text":
|
||||
print(f"Text:\n{block.text}\n")
|
||||
```
|
||||
|
||||
### OpenAI SDK via LiteLLM Proxy
|
||||
|
||||
```python
|
||||
import os
|
||||
os.environ["OPENAI_BASE_URL"] = "http://localhost:4000"
|
||||
os.environ["OPENAI_API_KEY"] = "sk-1234" # Your LiteLLM proxy key
|
||||
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI()
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="minimax-m2-5",
|
||||
messages=[
|
||||
{"role": "system", "content": "You are a helpful assistant."},
|
||||
{"role": "user", "content": "Hi, how are you?"},
|
||||
],
|
||||
extra_body={"reasoning_split": True},
|
||||
)
|
||||
|
||||
# Access thinking and response
|
||||
if hasattr(response.choices[0].message, 'reasoning_details'):
|
||||
print(f"Thinking:\n{response.choices[0].message.reasoning_details[0]['text']}\n")
|
||||
print(f"Text:\n{response.choices[0].message.content}\n")
|
||||
```
|
||||
|
|
@ -93,6 +93,12 @@ Implement `POST /beta/litellm_basic_guardrail_api`
|
|||
"user_api_key_end_user_id": "end user id associated with the litellm virtual key used",
|
||||
"user_api_key_org_id": "org id associated with the litellm virtual key used"
|
||||
},
|
||||
"request_headers": { // optional: inbound request headers (allowlist). Allowed headers show their value; all others show "[present]" to indicate the header existed.
|
||||
"User-Agent": "OpenAI/Python 2.17.0",
|
||||
"Content-Type": "application/json",
|
||||
"X-Request-Id": "[present]"
|
||||
},
|
||||
"litellm_version": "1.x.y", // optional: LiteLLM library version running this proxy
|
||||
"input_type": "request", // "request" or "response"
|
||||
"litellm_call_id": "unique_call_id", // the call id of the individual LLM call
|
||||
"litellm_trace_id": "trace_id", // the trace id of the LLM call - useful if there are multiple LLM calls for the same conversation
|
||||
|
|
|
|||
|
|
@ -5,6 +5,13 @@ import Image from '@theme/IdealImage';
|
|||
|
||||
Benchmarks for LiteLLM Gateway (Proxy Server) tested against a fake OpenAI endpoint.
|
||||
|
||||
## Setting Up a Fake OpenAI Endpoint
|
||||
|
||||
For load testing and benchmarking, you can use a fake OpenAI proxy server. LiteLLM provides:
|
||||
|
||||
1. **Hosted endpoint**: Use our free hosted fake endpoint at `https://exampleopenaiendpoint-production.up.railway.app/`
|
||||
2. **Self-hosted**: Set up your own fake OpenAI proxy server using [github.com/BerriAI/example_openai_endpoint](https://github.com/BerriAI/example_openai_endpoint)
|
||||
|
||||
Use this config for testing:
|
||||
|
||||
```yaml
|
||||
|
|
@ -12,7 +19,7 @@ model_list:
|
|||
- model_name: "fake-openai-endpoint"
|
||||
litellm_params:
|
||||
model: openai/any
|
||||
api_base: https://your-fake-openai-endpoint.com/chat/completions
|
||||
api_base: https://exampleopenaiendpoint-production.up.railway.app/ # or your self-hosted endpoint
|
||||
api_key: "test"
|
||||
```
|
||||
|
||||
|
|
|
|||
|
|
@ -18,7 +18,7 @@ Each provider uses their own search backend:
|
|||
|
||||
| Provider | Search Engine | Notes |
|
||||
|----------|---------------|-------|
|
||||
| **OpenAI** (`gpt-4o-search-preview`, `gpt-4o-mini-search-preview`, `gpt-5-search-api`) | OpenAI's internal search | Real-time web data |
|
||||
| **OpenAI** (`gpt-5-search-api`, `gpt-4o-search-preview`, `gpt-4o-mini-search-preview`) | OpenAI's internal search | Real-time web data |
|
||||
| **xAI** (`grok-3`) | xAI's search + X/Twitter | Real-time social media data |
|
||||
| **Google AI/Vertex** (`gemini-2.0-flash`) | **Google Search** | Uses actual Google search results |
|
||||
| **Anthropic** (`claude-3-5-sonnet`) | Anthropic's web search | Real-time web data |
|
||||
|
|
@ -45,6 +45,19 @@ Use `web_search_options` when you need to:
|
|||
**Anthropic Web Search Models**: Claude models that support web search: `claude-3-5-sonnet-latest`, `claude-3-5-sonnet-20241022`, `claude-3-5-haiku-latest`, `claude-3-5-haiku-20241022`, `claude-3-7-sonnet-20250219`
|
||||
:::
|
||||
|
||||
## OpenAI Web Search: Two Approaches
|
||||
|
||||
OpenAI offers two distinct ways to use web search depending on the endpoint and model:
|
||||
|
||||
| Approach | Endpoint | Models | How to enable |
|
||||
|----------|----------|--------|---------------|
|
||||
| **Search Models** | `/chat/completions` | `gpt-5-search-api`, `gpt-4o-search-preview`, `gpt-4o-mini-search-preview` | Pass `web_search_options` parameter |
|
||||
| **Web Search Tool** | `/responses` | `gpt-5`, `gpt-4.1`, `gpt-4o`, and other regular models | Pass `web_search_preview` tool |
|
||||
|
||||
:::tip Search models search automatically
|
||||
Search models like `gpt-5-search-api` **automatically search the web** even without the `web_search_options` parameter. Use `web_search_options` to set `search_context_size` (`"low"`, `"medium"`, `"high"`) or specify `user_location` for localized results.
|
||||
:::
|
||||
|
||||
## `/chat/completions` (litellm.completion)
|
||||
|
||||
### Quick Start
|
||||
|
|
@ -56,7 +69,7 @@ Use `web_search_options` when you need to:
|
|||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="openai/gpt-4o-search-preview",
|
||||
model="openai/gpt-5-search-api",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
|
|
@ -76,31 +89,36 @@ response = completion(
|
|||
|
||||
```yaml
|
||||
model_list:
|
||||
# OpenAI
|
||||
# OpenAI search models
|
||||
- model_name: gpt-5-search-api
|
||||
litellm_params:
|
||||
model: openai/gpt-5-search-api
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
- model_name: gpt-4o-search-preview
|
||||
litellm_params:
|
||||
model: openai/gpt-4o-search-preview
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
|
||||
# xAI
|
||||
- model_name: grok-3
|
||||
litellm_params:
|
||||
model: xai/grok-3
|
||||
api_key: os.environ/XAI_API_KEY
|
||||
|
||||
|
||||
# Anthropic
|
||||
- model_name: claude-3-5-sonnet-latest
|
||||
litellm_params:
|
||||
model: anthropic/claude-3-5-sonnet-latest
|
||||
api_key: os.environ/ANTHROPIC_API_KEY
|
||||
|
||||
|
||||
# VertexAI
|
||||
- model_name: gemini-2-flash
|
||||
litellm_params:
|
||||
model: gemini-2.0-flash
|
||||
vertex_project: your-project-id
|
||||
vertex_location: us-central1
|
||||
|
||||
|
||||
# Google AI Studio
|
||||
- model_name: gemini-2-flash-studio
|
||||
litellm_params:
|
||||
|
|
@ -108,13 +126,13 @@ model_list:
|
|||
api_key: os.environ/GOOGLE_API_KEY
|
||||
```
|
||||
|
||||
2. Start the proxy
|
||||
2. Start the proxy
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
3. Test it!
|
||||
3. Test it!
|
||||
|
||||
```python showLineNumbers
|
||||
from openai import OpenAI
|
||||
|
|
@ -126,13 +144,18 @@ client = OpenAI(
|
|||
)
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="grok-3", # or any other web search enabled model
|
||||
model="gpt-5-search-api", # or any other web search enabled model
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What was a positive news story from today?"
|
||||
}
|
||||
]
|
||||
],
|
||||
extra_body={
|
||||
"web_search_options": {
|
||||
"search_context_size": "medium"
|
||||
}
|
||||
}
|
||||
)
|
||||
```
|
||||
</TabItem>
|
||||
|
|
@ -149,7 +172,7 @@ from litellm import completion
|
|||
|
||||
# Customize search context size
|
||||
response = completion(
|
||||
model="openai/gpt-4o-search-preview",
|
||||
model="openai/gpt-5-search-api",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
|
|
@ -257,6 +280,12 @@ response = client.chat.completions.create(
|
|||
|
||||
## `/responses` (litellm.responses)
|
||||
|
||||
Use the `web_search_preview` tool with models like `gpt-5`, `gpt-4.1`, `gpt-4o`, etc.
|
||||
|
||||
:::info
|
||||
Search-dedicated models like `gpt-5-search-api` and `gpt-4o-search-preview` do **not** support the `/responses` endpoint. Use them with `/chat/completions` + `web_search_options` instead (see above).
|
||||
:::
|
||||
|
||||
### Quick Start
|
||||
|
||||
<Tabs>
|
||||
|
|
@ -266,18 +295,14 @@ response = client.chat.completions.create(
|
|||
from litellm import responses
|
||||
|
||||
response = responses(
|
||||
model="openai/gpt-4o",
|
||||
input=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What was a positive news story from today?"
|
||||
}
|
||||
],
|
||||
model="openai/gpt-5",
|
||||
input="What is the capital of France?",
|
||||
tools=[{
|
||||
"type": "web_search_preview" # enables web search with default medium context size
|
||||
}]
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
|
|
@ -285,19 +310,24 @@ response = responses(
|
|||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-4o
|
||||
- model_name: gpt-5
|
||||
litellm_params:
|
||||
model: openai/gpt-4o
|
||||
model: openai/gpt-5
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
- model_name: gpt-4.1
|
||||
litellm_params:
|
||||
model: openai/gpt-4.1
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
```
|
||||
|
||||
2. Start the proxy
|
||||
2. Start the proxy
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
3. Test it!
|
||||
3. Test it!
|
||||
|
||||
```python showLineNumbers
|
||||
from openai import OpenAI
|
||||
|
|
@ -309,11 +339,11 @@ client = OpenAI(
|
|||
)
|
||||
|
||||
response = client.responses.create(
|
||||
model="gpt-4o",
|
||||
model="gpt-5",
|
||||
tools=[{
|
||||
"type": "web_search_preview"
|
||||
}],
|
||||
input="What was a positive news story from today?",
|
||||
input="What is the capital of France?",
|
||||
)
|
||||
|
||||
print(response.output_text)
|
||||
|
|
@ -331,13 +361,8 @@ from litellm import responses
|
|||
|
||||
# Customize search context size
|
||||
response = responses(
|
||||
model="openai/gpt-4o",
|
||||
input=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What was a positive news story from today?"
|
||||
}
|
||||
],
|
||||
model="openai/gpt-5",
|
||||
input="What is the capital of France?",
|
||||
tools=[{
|
||||
"type": "web_search_preview",
|
||||
"search_context_size": "low" # Options: "low", "medium" (default), "high"
|
||||
|
|
@ -358,12 +383,12 @@ client = OpenAI(
|
|||
|
||||
# Customize search context size
|
||||
response = client.responses.create(
|
||||
model="gpt-4o",
|
||||
model="gpt-5",
|
||||
tools=[{
|
||||
"type": "web_search_preview",
|
||||
"search_context_size": "low" # Options: "low", "medium" (default), "high"
|
||||
}],
|
||||
input="What was a positive news story from today?",
|
||||
input="What is the capital of France?",
|
||||
)
|
||||
|
||||
print(response.output_text)
|
||||
|
|
@ -417,14 +442,14 @@ model_list:
|
|||
web_search_options:
|
||||
search_context_size: "high" # Options: "low", "medium", "high"
|
||||
|
||||
# Different context size for different models
|
||||
- model_name: gpt-4o-search-preview
|
||||
# OpenAI search model with custom context size
|
||||
- model_name: gpt-5-search-api
|
||||
litellm_params:
|
||||
model: openai/gpt-4o-search-preview
|
||||
model: openai/gpt-5-search-api
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
web_search_options:
|
||||
search_context_size: "low"
|
||||
|
||||
|
||||
# Gemini with medium context (default)
|
||||
- model_name: gemini-2-flash
|
||||
litellm_params:
|
||||
|
|
@ -449,6 +474,7 @@ Use `litellm.supports_web_search(model="model_name")` -> returns `True` if model
|
|||
|
||||
```python showLineNumbers
|
||||
# Check OpenAI models
|
||||
assert litellm.supports_web_search(model="openai/gpt-5-search-api") == True
|
||||
assert litellm.supports_web_search(model="openai/gpt-4o-search-preview") == True
|
||||
|
||||
# Check xAI models
|
||||
|
|
@ -472,13 +498,20 @@ assert litellm.supports_web_search(model="gemini/gemini-2.0-flash") == True
|
|||
```yaml
|
||||
model_list:
|
||||
# OpenAI
|
||||
- model_name: gpt-5-search-api
|
||||
litellm_params:
|
||||
model: openai/gpt-5-search-api
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
model_info:
|
||||
supports_web_search: True
|
||||
|
||||
- model_name: gpt-4o-search-preview
|
||||
litellm_params:
|
||||
model: openai/gpt-4o-search-preview
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
model_info:
|
||||
supports_web_search: True
|
||||
|
||||
|
||||
# xAI
|
||||
- model_name: grok-3
|
||||
litellm_params:
|
||||
|
|
@ -533,6 +566,12 @@ Expected Response
|
|||
```json showLineNumbers
|
||||
{
|
||||
"data": [
|
||||
{
|
||||
"model_group": "gpt-5-search-api",
|
||||
"providers": ["openai"],
|
||||
"max_tokens": 128000,
|
||||
"supports_web_search": true
|
||||
},
|
||||
{
|
||||
"model_group": "gpt-4o-search-preview",
|
||||
"providers": ["openai"],
|
||||
|
|
|
|||
|
|
@ -4,8 +4,9 @@ import Image from '@theme/IdealImage';
|
|||
|
||||
## Locust Load Test LiteLLM Proxy
|
||||
|
||||
1. Add `fake-openai-endpoint` to your proxy config.yaml and start your litellm proxy
|
||||
litellm provides a free hosted `fake-openai-endpoint` you can load test against
|
||||
1. Add `fake-openai-endpoint` to your proxy config.yaml and start your litellm proxy.
|
||||
|
||||
LiteLLM provides a free hosted `fake-openai-endpoint` you can load test against. You can also self-host your own fake OpenAI proxy server using [github.com/BerriAI/example_openai_endpoint](https://github.com/BerriAI/example_openai_endpoint).
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
|
|
|
|||
|
|
@ -29,12 +29,16 @@ Tutorial on how to get to 1K+ RPS with LiteLLM Proxy on locust
|
|||
|
||||
**Note:** we're currently migrating to aiohttp which has 10x higher throughput. We recommend using the `openai/` provider for load testing.
|
||||
|
||||
:::tip Setting Up a Fake OpenAI Endpoint
|
||||
You can use our hosted fake endpoint or self-host your own using [github.com/BerriAI/example_openai_endpoint](https://github.com/BerriAI/example_openai_endpoint).
|
||||
:::
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: "fake-openai-endpoint"
|
||||
litellm_params:
|
||||
model: openai/any
|
||||
api_base: https://your-fake-openai-endpoint.com/chat/completions
|
||||
api_base: https://exampleopenaiendpoint-production.up.railway.app/ # or your self-hosted endpoint
|
||||
api_key: "test"
|
||||
```
|
||||
|
||||
|
|
|
|||
|
|
@ -242,3 +242,96 @@ curl http://localhost:4000/mcp-rest/tools/call \
|
|||
| `client_secret` | Yes | OAuth2 client secret. Supports `os.environ/VAR_NAME` |
|
||||
| `token_url` | Yes | Token endpoint URL |
|
||||
| `scopes` | No | List of scopes to request |
|
||||
|
||||
## Debugging OAuth
|
||||
|
||||
When the LiteLLM proxy is hosted remotely and you cannot access server logs, enable **debug headers** to get masked authentication diagnostics in the HTTP response.
|
||||
|
||||
### Enable Debug Mode
|
||||
|
||||
Add the `x-litellm-mcp-debug: true` header to your MCP client request.
|
||||
|
||||
**Claude Code:**
|
||||
|
||||
```bash
|
||||
claude mcp add --transport http litellm_proxy http://proxy.example.com/atlassian_mcp/mcp \
|
||||
--header "x-litellm-api-key: Bearer sk-..." \
|
||||
--header "x-litellm-mcp-debug: true"
|
||||
```
|
||||
|
||||
**curl:**
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/atlassian_mcp/mcp \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "x-litellm-api-key: Bearer sk-..." \
|
||||
-H "x-litellm-mcp-debug: true" \
|
||||
-d '{"jsonrpc":"2.0","id":1,"method":"tools/list","params":{}}'
|
||||
```
|
||||
|
||||
### Reading the Debug Response Headers
|
||||
|
||||
The response includes these headers (all sensitive values are masked):
|
||||
|
||||
| Header | Description |
|
||||
|--------|-------------|
|
||||
| `x-mcp-debug-inbound-auth` | Which inbound auth headers were present. |
|
||||
| `x-mcp-debug-oauth2-token` | The OAuth2 token (masked). Shows `SAME_AS_LITELLM_KEY` if the LiteLLM key is leaking. |
|
||||
| `x-mcp-debug-auth-resolution` | Which auth method was used: `oauth2-passthrough`, `m2m-client-credentials`, `per-request-header`, `static-token`, or `no-auth`. |
|
||||
| `x-mcp-debug-outbound-url` | The upstream MCP server URL. |
|
||||
| `x-mcp-debug-server-auth-type` | The `auth_type` configured on the server. |
|
||||
|
||||
**Example — healthy OAuth2 passthrough:**
|
||||
|
||||
```
|
||||
x-mcp-debug-inbound-auth: x-litellm-api-key=Bearer****1234; authorization=Bearer****ef01
|
||||
x-mcp-debug-oauth2-token: Bearer****ef01
|
||||
x-mcp-debug-auth-resolution: oauth2-passthrough
|
||||
x-mcp-debug-outbound-url: https://mcp.atlassian.com/v1/mcp
|
||||
x-mcp-debug-server-auth-type: oauth2
|
||||
```
|
||||
|
||||
**Example — LiteLLM key leaking (misconfigured):**
|
||||
|
||||
```
|
||||
x-mcp-debug-inbound-auth: authorization=Bearer****1234
|
||||
x-mcp-debug-oauth2-token: Bearer****1234 (SAME_AS_LITELLM_KEY - likely misconfigured)
|
||||
x-mcp-debug-auth-resolution: oauth2-passthrough
|
||||
x-mcp-debug-outbound-url: https://mcp.atlassian.com/v1/mcp
|
||||
x-mcp-debug-server-auth-type: oauth2
|
||||
```
|
||||
|
||||
### Common Issues
|
||||
|
||||
#### LiteLLM API key leaking to the MCP server
|
||||
|
||||
**Symptom:** `x-mcp-debug-oauth2-token` shows `SAME_AS_LITELLM_KEY`.
|
||||
|
||||
The `Authorization` header carries the LiteLLM API key instead of an OAuth2 token. The OAuth2 flow never ran because the client already had an `Authorization` header set.
|
||||
|
||||
**Fix:** Move the LiteLLM key to `x-litellm-api-key`:
|
||||
|
||||
```bash
|
||||
# WRONG — blocks OAuth2 discovery
|
||||
claude mcp add --transport http my_server http://proxy/mcp/server \
|
||||
--header "Authorization: Bearer sk-..."
|
||||
|
||||
# CORRECT — LiteLLM key in dedicated header, Authorization free for OAuth2
|
||||
claude mcp add --transport http my_server http://proxy/mcp/server \
|
||||
--header "x-litellm-api-key: Bearer sk-..."
|
||||
```
|
||||
|
||||
#### No OAuth2 token present
|
||||
|
||||
**Symptom:** `x-mcp-debug-oauth2-token` shows `(none)` and `x-mcp-debug-auth-resolution` shows `no-auth`.
|
||||
|
||||
Check that:
|
||||
1. The `Authorization` header is NOT set as a static header in the client config.
|
||||
2. The MCP server in LiteLLM config has `auth_type: oauth2`.
|
||||
3. The `.well-known/oauth-protected-resource` endpoint returns valid metadata.
|
||||
|
||||
#### M2M token used instead of user token
|
||||
|
||||
**Symptom:** `x-mcp-debug-auth-resolution` shows `m2m-client-credentials`.
|
||||
|
||||
The server has `client_id`/`client_secret`/`token_url` configured so LiteLLM is fetching a machine-to-machine token instead of using the per-user OAuth2 token. To use per-user tokens, remove the client credentials from the server config.
|
||||
|
|
|
|||
|
|
@ -6,6 +6,39 @@ When LiteLLM acts as an MCP proxy, traffic normally flows `Client → LiteLLM Pr
|
|||
|
||||
For provisioning steps, transport options, and configuration fields, refer to [mcp.md](./mcp.md).
|
||||
|
||||
## Quick Start: Debug with One Command
|
||||
|
||||
The fastest way to debug MCP issues is to enable **debug headers**. Run this curl against your LiteLLM proxy and check the response headers:
|
||||
|
||||
```bash
|
||||
curl -si -X POST http://localhost:4000/{your_mcp_server}/mcp \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "x-litellm-api-key: Bearer sk-YOUR_KEY" \
|
||||
-H "x-litellm-mcp-debug: true" \
|
||||
-d '{"jsonrpc":"2.0","id":1,"method":"tools/list","params":{}}' \
|
||||
2>&1 | grep -i "x-mcp-debug"
|
||||
```
|
||||
|
||||
This returns masked diagnostic headers that tell you exactly what's happening with authentication:
|
||||
|
||||
```
|
||||
x-mcp-debug-inbound-auth: x-litellm-api-key=Bearer****1234
|
||||
x-mcp-debug-oauth2-token: Bearer****ef01
|
||||
x-mcp-debug-auth-resolution: oauth2-passthrough
|
||||
x-mcp-debug-outbound-url: https://mcp.atlassian.com/v1/mcp
|
||||
x-mcp-debug-server-auth-type: oauth2
|
||||
```
|
||||
|
||||
If you see `SAME_AS_LITELLM_KEY` in `x-mcp-debug-oauth2-token`, your LiteLLM API key is leaking to the MCP server instead of an OAuth2 token. See [Debugging OAuth](./mcp_oauth#debugging-oauth) for the fix and other common issues.
|
||||
|
||||
For Claude Code, add the debug header to your MCP config:
|
||||
|
||||
```bash
|
||||
claude mcp add --transport http my_server http://localhost:4000/my_mcp/mcp \
|
||||
--header "x-litellm-api-key: Bearer sk-..." \
|
||||
--header "x-litellm-mcp-debug: true"
|
||||
```
|
||||
|
||||
## Locate the Error Source
|
||||
|
||||
Pin down where the failure occurs before adjusting settings so you do not mix symptoms from separate hops.
|
||||
|
|
@ -13,7 +46,7 @@ Pin down where the failure occurs before adjusting settings so you do not mix sy
|
|||
### LiteLLM UI / Playground Errors (LiteLLM → MCP)
|
||||
Failures shown on the MCP creation form or within the MCP Tool Testing Playground mean the LiteLLM proxy cannot reach the MCP server. Typical causes are misconfiguration (transport, headers, credentials), MCP/server outages, network/firewall blocks, or inaccessible OAuth metadata.
|
||||
|
||||
<Image
|
||||
<Image
|
||||
img={require('../img/mcp_tool_testing_playground.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0'}}
|
||||
/>
|
||||
|
|
@ -22,7 +55,7 @@ Failures shown on the MCP creation form or within the MCP Tool Testing Playgroun
|
|||
|
||||
**Actions**
|
||||
- Capture LiteLLM proxy logs alongside MCP-server logs (see [Error Log Example](./mcp_troubleshoot#error-log-example-failed-mcp-call)) to inspect the request/response pair and stack traces.
|
||||
- From the LiteLLM server, run Method 2 ([`curl` smoke test](./mcp_troubleshoot#curl-smoke-test)) against the MCP endpoint to confirm basic connectivity.
|
||||
- From the LiteLLM server, run a [`curl` smoke test](./mcp_troubleshoot#curl-smoke-test) against the MCP endpoint to confirm basic connectivity.
|
||||
|
||||
### Client Traffic Issues (Client → LiteLLM)
|
||||
If only real client requests fail, determine whether LiteLLM ever reaches the MCP hop.
|
||||
|
|
@ -43,7 +76,7 @@ During `/responses` or `/chat/completions`, LiteLLM may trigger MCP tool calls m
|
|||
- Validate MCP connectivity with the [MCP Inspector](./mcp_troubleshoot#mcp-inspector) to ensure the server responds.
|
||||
- Reproduce the same MCP call via the LiteLLM Playground to confirm LiteLLM can complete the MCP hop independently.
|
||||
|
||||
<Image
|
||||
<Image
|
||||
img={require('../img/mcp_playground.png')}
|
||||
style={{width: '80%', display: 'block', margin: '0'}}
|
||||
/>
|
||||
|
|
@ -55,6 +88,10 @@ LiteLLM performs metadata discovery per the MCP spec ([section 2.3](https://mode
|
|||
- Use `curl <metadata_url>` (or similar) from the LiteLLM host to ensure the discovery document is reachable and contains the expected authorization/token endpoints.
|
||||
- Record the exact metadata URL, requested scopes, and any static client credentials so support can replay the discovery step if needed.
|
||||
|
||||
## Debugging OAuth
|
||||
|
||||
For detailed OAuth2 debugging — including debug header reference, common misconfigurations, and example output — see [Debugging OAuth](./mcp_oauth#debugging-oauth).
|
||||
|
||||
## Verify Connectivity
|
||||
|
||||
Run lightweight validations before impacting production traffic.
|
||||
|
|
@ -66,7 +103,7 @@ Use the MCP Inspector when you need to test both `Client → LiteLLM` and `Clien
|
|||
2. Configure and connect:
|
||||
- **Transport Type:** choose the transport the client uses (Streamable HTTP for LiteLLM).
|
||||
- **URL:** the endpoint under test (LiteLLM MCP URL for `Client → LiteLLM`, or the MCP server URL for `Client → MCP`).
|
||||
- **Custom Headers:** e.g., `Authorization: Bearer <LiteLLM API Key>`.
|
||||
- **Custom Headers:** e.g., `x-litellm-api-key: Bearer <LiteLLM API Key>`.
|
||||
3. Open the **Tools** tab and click **List Tools** to verify the MCP alias responds.
|
||||
|
||||
### `curl` Smoke Test
|
||||
|
|
@ -79,7 +116,7 @@ curl -X POST https://your-target-domain.example.com/mcp \
|
|||
-d '{"jsonrpc":"2.0","id":1,"method":"tools/list","params":{}}'
|
||||
```
|
||||
|
||||
Add `-H "Authorization: Bearer <LiteLLM API Key>"` when the target is a LiteLLM endpoint that requires authentication. Adjust the headers, or payload to target other MCP methods. Matching failures between `curl` and LiteLLM confirm that the MCP server or network/OAuth layer is the culprit.
|
||||
Add `-H "x-litellm-api-key: Bearer <LiteLLM API Key>"` when the target is a LiteLLM endpoint that requires authentication. Adjust the headers or payload to target other MCP methods. Matching failures between `curl` and LiteLLM confirm that the MCP server or network/OAuth layer is the culprit.
|
||||
|
||||
## Review Logs
|
||||
|
||||
|
|
|
|||
|
|
@ -1,22 +1,121 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# OpenAI Agents SDK
|
||||
|
||||
The [OpenAI Agents SDK](https://github.com/openai/openai-agents-python) is a lightweight framework for building multi-agent workflows.
|
||||
It includes an official LiteLLM extension that lets you use any of the 100+ supported providers (Anthropic, Gemini, Mistral, Bedrock, etc.)
|
||||
Use OpenAI Agents SDK with any LLM provider through LiteLLM Proxy.
|
||||
|
||||
The [OpenAI Agents SDK](https://github.com/openai/openai-agents-python) is a lightweight framework for building multi-agent workflows. It includes an official LiteLLM extension that lets you use any of the 100+ supported providers.
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Install Dependencies
|
||||
|
||||
```bash
|
||||
pip install "openai-agents[litellm]"
|
||||
```
|
||||
|
||||
### 2. Add Model to Config
|
||||
|
||||
```yaml title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4o
|
||||
litellm_params:
|
||||
model: "openai/gpt-4o"
|
||||
api_key: "os.environ/OPENAI_API_KEY"
|
||||
|
||||
- model_name: claude-sonnet
|
||||
litellm_params:
|
||||
model: "anthropic/claude-3-5-sonnet-20241022"
|
||||
api_key: "os.environ/ANTHROPIC_API_KEY"
|
||||
|
||||
- model_name: gemini-pro
|
||||
litellm_params:
|
||||
model: "gemini/gemini-2.0-flash-exp"
|
||||
api_key: "os.environ/GEMINI_API_KEY"
|
||||
```
|
||||
|
||||
### 3. Start LiteLLM Proxy
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
### 4. Use with Proxy
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="proxy" label="Via Proxy">
|
||||
|
||||
```python
|
||||
from agents import Agent, Runner
|
||||
from agents.extensions.models.litellm_model import LitellmModel
|
||||
|
||||
# Point to LiteLLM proxy
|
||||
agent = Agent(
|
||||
name="Assistant",
|
||||
instructions="You are a helpful assistant.",
|
||||
model=LitellmModel(model="provider/model-name")
|
||||
model=LitellmModel(
|
||||
model="claude-sonnet", # Model from config.yaml
|
||||
api_key="sk-1234", # LiteLLM API key
|
||||
base_url="http://localhost:4000"
|
||||
)
|
||||
)
|
||||
|
||||
result = Runner.run_sync(agent, "your_prompt_here")
|
||||
print("Result:", result.final_output)
|
||||
result = await Runner.run(agent, "What is LiteLLM?")
|
||||
print(result.final_output)
|
||||
```
|
||||
|
||||
- [GitHub](https://github.com/openai/openai-agents-python)
|
||||
- [LiteLLM Extension Docs](https://openai.github.io/openai-agents-python/ref/extensions/litellm/)
|
||||
</TabItem>
|
||||
<TabItem value="direct" label="Direct (No Proxy)">
|
||||
|
||||
```python
|
||||
from agents import Agent, Runner
|
||||
from agents.extensions.models.litellm_model import LitellmModel
|
||||
|
||||
# Use any provider directly
|
||||
agent = Agent(
|
||||
name="Assistant",
|
||||
instructions="You are a helpful assistant.",
|
||||
model=LitellmModel(
|
||||
model="anthropic/claude-3-5-sonnet-20241022",
|
||||
api_key="your-anthropic-key"
|
||||
)
|
||||
)
|
||||
|
||||
result = await Runner.run(agent, "What is LiteLLM?")
|
||||
print(result.final_output)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Track Usage
|
||||
|
||||
Enable usage tracking to monitor token consumption:
|
||||
|
||||
```python
|
||||
from agents import Agent, ModelSettings
|
||||
from agents.extensions.models.litellm_model import LitellmModel
|
||||
|
||||
agent = Agent(
|
||||
name="Assistant",
|
||||
model=LitellmModel(model="claude-sonnet", api_key="sk-1234"),
|
||||
model_settings=ModelSettings(include_usage=True)
|
||||
)
|
||||
|
||||
result = await Runner.run(agent, "Hello")
|
||||
print(result.context_wrapper.usage) # Token counts
|
||||
```
|
||||
|
||||
## Environment Variables
|
||||
|
||||
| Variable | Value | Description |
|
||||
|----------|-------|-------------|
|
||||
| `LITELLM_BASE_URL` | `http://localhost:4000` | LiteLLM proxy URL |
|
||||
| `LITELLM_API_KEY` | `sk-1234` | Your LiteLLM API key |
|
||||
|
||||
## Related Resources
|
||||
|
||||
- [OpenAI Agents SDK Documentation](https://openai.github.io/openai-agents-python/)
|
||||
- [LiteLLM Extension Docs](https://openai.github.io/openai-agents-python/models/litellm/)
|
||||
- [LiteLLM Proxy Quick Start](../proxy/quick_start)
|
||||
|
|
|
|||
|
|
@ -1473,6 +1473,20 @@ LiteLLM translates OpenAI's `reasoning_effort` to Anthropic's `thinking` paramet
|
|||
| "medium" | "budget_tokens": 2048 |
|
||||
| "high" | "budget_tokens": 4096 |
|
||||
|
||||
:::note
|
||||
For Claude Opus 4.6, all `reasoning_effort` values (`low`, `medium`, `high`) are mapped to `thinking: {type: "adaptive"}`. To use explicit thinking budgets, pass the native `thinking` parameter directly:
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
resp = completion(
|
||||
model="anthropic/claude-opus-4-6",
|
||||
messages=[{"role": "user", "content": "What is the capital of France?"}],
|
||||
thinking={"type": "enabled", "budget_tokens": 1024},
|
||||
)
|
||||
```
|
||||
:::
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
|
|
@ -1614,8 +1628,65 @@ curl http://0.0.0.0:4000/v1/chat/completions \
|
|||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
#### Adaptive Thinking (Claude Opus 4.6)
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-opus-4-6",
|
||||
messages=[{"role": "user", "content": "What is the optimal strategy for solving this problem?"}],
|
||||
thinking={"type": "adaptive"},
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer $LITELLM_KEY" \
|
||||
-d '{
|
||||
"model": "anthropic/claude-opus-4-6",
|
||||
"messages": [{"role": "user", "content": "What is the optimal strategy for solving this problem?"}],
|
||||
"thinking": {"type": "adaptive"}
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
#### Enabled Thinking with Budget
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="anthropic/claude-opus-4-6",
|
||||
messages=[{"role": "user", "content": "What is the capital of France?"}],
|
||||
thinking={"type": "enabled", "budget_tokens": 5000},
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer $LITELLM_KEY" \
|
||||
-d '{
|
||||
"model": "anthropic/claude-opus-4-6",
|
||||
"messages": [{"role": "user", "content": "What is the capital of France?"}],
|
||||
"thinking": {"type": "enabled", "budget_tokens": 5000}
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## **Passing Extra Headers to Anthropic API**
|
||||
|
||||
|
|
|
|||
|
|
@ -1,7 +1,7 @@
|
|||
# Dashscope (Qwen API)
|
||||
# Dashscope API (Qwen models)
|
||||
https://dashscope.console.aliyun.com/
|
||||
|
||||
**We support ALL Qwen models, just set `dashscope/` as a prefix when sending completion requests**
|
||||
**We support ALL Qwen models (from Alibaba Cloud), just set `dashscope/` as a prefix when sending completion requests**
|
||||
|
||||
## API Key
|
||||
```python
|
||||
|
|
@ -9,6 +9,26 @@ https://dashscope.console.aliyun.com/
|
|||
os.environ['DASHSCOPE_API_KEY']
|
||||
```
|
||||
|
||||
## API Base
|
||||
You can optionally specify the API base URL depending on your region:
|
||||
|
||||
| Region | API Base |
|
||||
|--------|----------|
|
||||
| **International** | `https://dashscope-intl.aliyuncs.com/compatible-mode/v1` |
|
||||
| **China/Beijing** | `https://dashscope.aliyuncs.com/compatible-mode/v1` |
|
||||
|
||||
```python
|
||||
# Set via environment variable
|
||||
os.environ['DASHSCOPE_API_BASE'] = "https://dashscope-intl.aliyuncs.com/compatible-mode/v1"
|
||||
|
||||
# Or pass directly in the completion call
|
||||
response = completion(
|
||||
model="dashscope/qwen-turbo",
|
||||
messages=[{"role": "user", "content": "hello"}],
|
||||
api_base="https://dashscope-intl.aliyuncs.com/compatible-mode/v1"
|
||||
)
|
||||
```
|
||||
|
||||
## Sample Usage
|
||||
```python
|
||||
from litellm import completion
|
||||
|
|
@ -43,9 +63,7 @@ for chunk in response:
|
|||
```
|
||||
|
||||
|
||||
## Supported Models - ALL Qwen Models Supported!
|
||||
We support ALL Qwen models, just set `dashscope/` as a prefix when sending completion requests
|
||||
|
||||
## All supported Models
|
||||
|
||||
[DashScope Model List](https://help.aliyun.com/zh/model-studio/compatibility-of-openai-with-dashscope?spm=a2c4g.11186623.help-menu-2400256.d_2_8_0.1efd516e2tTXBn&scm=20140722.H_2833609._.OR_help-T_cn~zh-V_1#7f9c78ae99pwz)
|
||||
|
||||
|
|
|
|||
|
|
@ -230,7 +230,70 @@ os.environ["OPENAI_BASE_URL"] = "https://your_host/v1" # OPTIONAL
|
|||
|
||||
These also support the `OPENAI_BASE_URL` environment variable, which can be used to specify a custom API endpoint.
|
||||
|
||||
## OpenAI Vision Models
|
||||
### OpenAI Web Search Models
|
||||
|
||||
OpenAI has two ways to use web search, depending on the endpoint:
|
||||
|
||||
| Approach | Endpoint | Models | How to enable |
|
||||
|----------|----------|--------|---------------|
|
||||
| **Search Models** | `/chat/completions` | `gpt-5-search-api`, `gpt-4o-search-preview`, `gpt-4o-mini-search-preview` | Pass `web_search_options` parameter |
|
||||
| **Web Search Tool** | `/responses` | `gpt-5`, `gpt-4.1`, `gpt-4o`, and other regular models | Pass `web_search_preview` tool |
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk-completion" label="SDK - /chat/completions">
|
||||
|
||||
```python showLineNumbers
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="openai/gpt-5-search-api",
|
||||
messages=[{"role": "user", "content": "What is the capital of France?"}],
|
||||
web_search_options={
|
||||
"search_context_size": "medium" # Options: "low", "medium", "high"
|
||||
}
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="sdk-responses" label="SDK - /responses">
|
||||
|
||||
```python showLineNumbers
|
||||
from litellm import responses
|
||||
|
||||
response = responses(
|
||||
model="openai/gpt-5",
|
||||
input="What is the capital of France?",
|
||||
tools=[{
|
||||
"type": "web_search_preview",
|
||||
"search_context_size": "low"
|
||||
}]
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
# Search model for /chat/completions
|
||||
- model_name: gpt-5-search-api
|
||||
litellm_params:
|
||||
model: openai/gpt-5-search-api
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
# Regular model for /responses with web_search_preview tool
|
||||
- model_name: gpt-5
|
||||
litellm_params:
|
||||
model: openai/gpt-5
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
For full details, see the [Web Search guide](../completion/web_search.md).
|
||||
|
||||
## OpenAI Vision Models
|
||||
| Model Name | Function Call |
|
||||
|-----------------------|-----------------------------------------------------------------|
|
||||
| gpt-4o | `response = completion(model="gpt-4o", messages=messages)` |
|
||||
|
|
|
|||
|
|
@ -37,6 +37,24 @@ for event in response:
|
|||
print(event)
|
||||
```
|
||||
|
||||
#### Web Search
|
||||
```python showLineNumbers title="OpenAI Responses with Web Search"
|
||||
import litellm
|
||||
|
||||
response = litellm.responses(
|
||||
model="openai/gpt-5",
|
||||
input="What is the capital of France?",
|
||||
tools=[{
|
||||
"type": "web_search_preview",
|
||||
"search_context_size": "medium" # Options: "low", "medium", "high"
|
||||
}]
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
For full details, see the [Web Search guide](../../completion/web_search.md).
|
||||
|
||||
#### Image Generation with Streaming
|
||||
```python showLineNumbers title="OpenAI Streaming Image Generation"
|
||||
import litellm
|
||||
|
|
|
|||
62
docs/my-website/docs/providers/scaleway.md
Normal file
62
docs/my-website/docs/providers/scaleway.md
Normal file
|
|
@ -0,0 +1,62 @@
|
|||
|
||||
# Scaleway
|
||||
LiteLLM supports all [models available on Scaleway Generative APIs ↗](https://www.scaleway.com/en/docs/generative-apis/reference-content/supported-models/).
|
||||
|
||||
## Usage with LiteLLM Python SDK
|
||||
|
||||
```python
|
||||
import os
|
||||
from litellm import completion
|
||||
|
||||
os.environ["SCW_SECRET_KEY"] = "your-scaleway-secret-key"
|
||||
|
||||
messages = [{"role": "user", "content": "Write a short poem"}]
|
||||
response = completion(model="scaleway/qwen3-235b-a22b-instruct-2507", messages=messages)
|
||||
print(response)
|
||||
```
|
||||
|
||||
## Usage with LiteLLM Proxy
|
||||
|
||||
### 1. Set Scaleway models in config.yaml
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: scaleway-model
|
||||
litellm_params:
|
||||
model: scaleway/qwen3-235b-a22b-instruct-2507
|
||||
api_key: "os.environ/SCW_SECRET_KEY" # ensure you have `SCW_SECRET_KEY` in your .env
|
||||
```
|
||||
|
||||
### 2. Start proxy
|
||||
|
||||
```bash
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
### 3. Query proxy
|
||||
|
||||
Assuming the proxy is running on [http://localhost:4000](http://localhost:4000):
|
||||
```bash
|
||||
curl http://localhost:4000/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer YOUR_LITELLM_MASTER_KEY" \
|
||||
-d '{
|
||||
"model": "scaleway-model",
|
||||
"messages": [
|
||||
{
|
||||
"role": "system",
|
||||
"content": "You are a helpful assistant."
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Write a short poem"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
`-H "Authorization: Bearer YOUR_LITELLM_MASTER_KEY" ` is only required if you have set a LiteLLM master key
|
||||
|
||||
|
||||
## Supported features
|
||||
|
||||
Scaleway provider supports all features in [Generative APIs reference documentation ↗](https://www.scaleway.com/en/developers/api/generative-apis/), such as streaming, structured outputs and tool calling.
|
||||
122
docs/my-website/docs/proxy/access_groups.md
Normal file
122
docs/my-website/docs/proxy/access_groups.md
Normal file
|
|
@ -0,0 +1,122 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Access Groups
|
||||
|
||||
Access Groups simplify how you define and manage resource access across your organization. Instead of configuring models, MCP servers, and agents separately on each key or team, you create one group that bundles the resources you want to grant, then attach that group to your keys or teams.
|
||||
|
||||
## Overview
|
||||
|
||||
**Access Groups** let you define a reusable set of allowed resources—models, MCP servers, and agents—in a single place. One group can grant access to all three resource types. Simply attach the group to a key or team, and they get access to everything defined in that group.
|
||||
|
||||
- **Unified resource control** – One group controls access to models, MCP servers, and agents together
|
||||
- **Reusable** – Define once, attach to many keys or teams
|
||||
- **Easy to maintain** – Update the group (add or remove resources) and all attached keys and teams automatically reflect the change
|
||||
- **Clear visibility** – See exactly which resources each group grants and which keys/teams use it
|
||||
|
||||
<Image img={require('../../img/ui_access_groups.png')} />
|
||||
|
||||
### How It Works
|
||||
|
||||
**Key concept:** Define resources in a group → Attach group to key or team → Key/team gets access to all resources in the group
|
||||
|
||||
| Resource Type | What the group controls |
|
||||
| --------------- | -------------------------------------------------------------------- |
|
||||
| **Models** | Which LLM models keys/teams can use (e.g., `gpt-4`, `claude-3-opus`) |
|
||||
| **MCP Servers** | Which MCP servers are available for tool calling |
|
||||
| **Agents** | Which agents can be invoked |
|
||||
|
||||
## How to Create and Use Access Groups in the UI
|
||||
|
||||
### 1. Navigate to Access Groups
|
||||
|
||||
Go to the Admin UI (e.g. `http://localhost:4000/ui` or your `PROXY_BASE_URL/ui`) and click **Access Groups** in the sidebar.
|
||||
|
||||
|
||||
|
||||
### 2. Create an Access Group
|
||||
|
||||
Click **Create Access Group** and give your group a name.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
### 3. Define Resources in the Group
|
||||
|
||||
Use the tabs to select which models, MCP servers, and agents this group grants access to:
|
||||
|
||||
- **Models tab** – Select the LLM models
|
||||
- **MCP Servers tab** – Select MCP servers (for tool calling)
|
||||
- **Agents tab** – Select agents
|
||||
|
||||
|
||||
|
||||
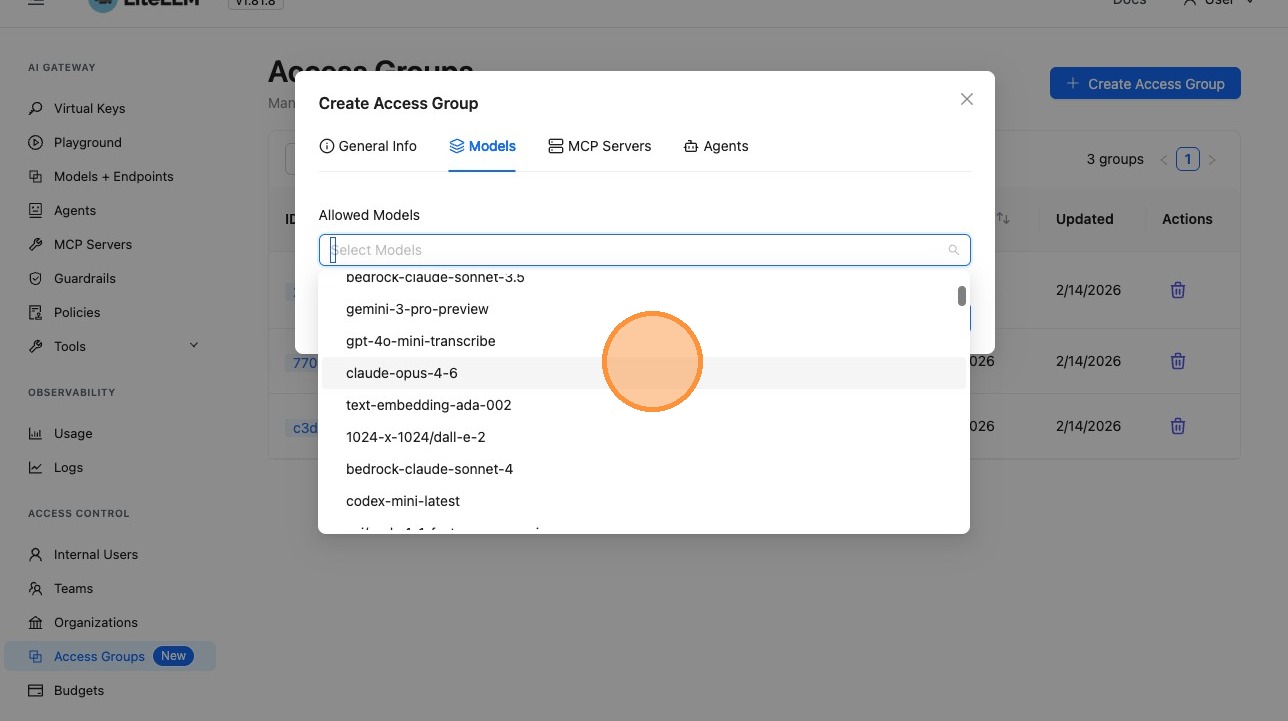
|
||||
|
||||
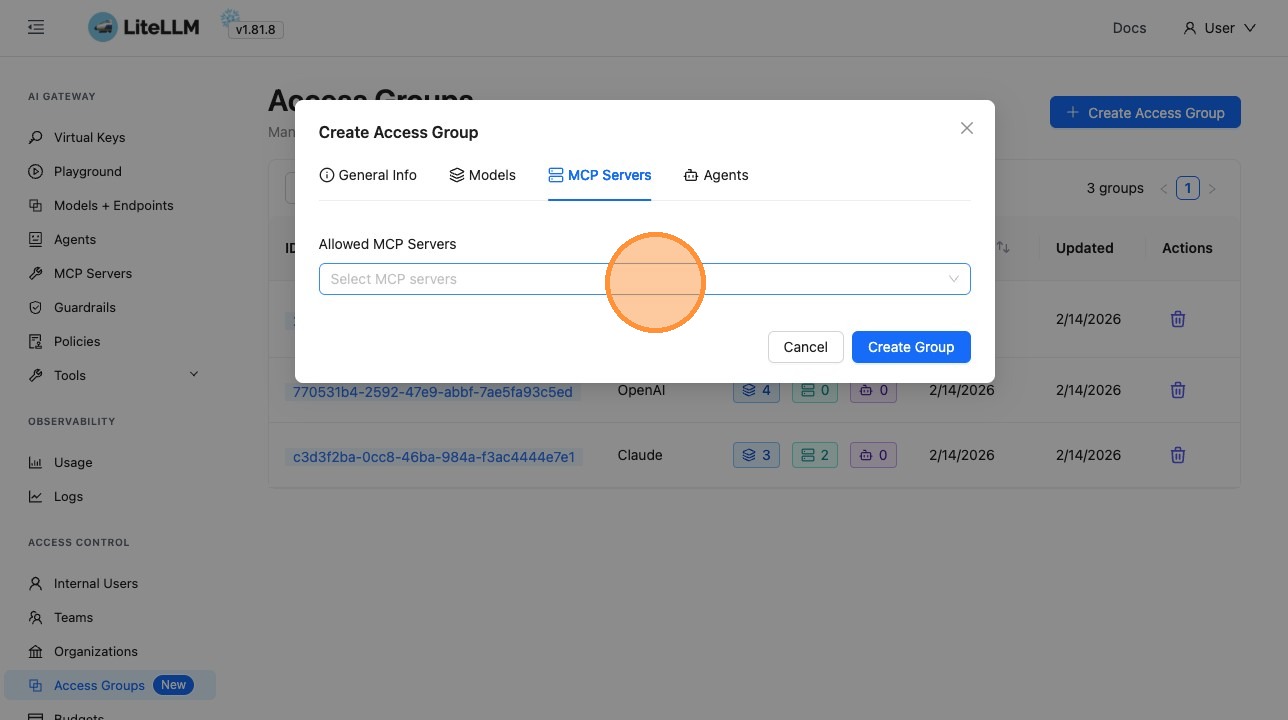
|
||||
|
||||
### 4. Attach the Access Group to a Key
|
||||
|
||||
When creating or editing a virtual key, expand **Optional Settings** and select your Access Group. The key will inherit access to all models, MCP servers, and agents defined in that group.
|
||||
|
||||
1. Go to **Virtual Keys** and click **+ Create New Key**
|
||||
2. Expand **Optional Settings**
|
||||
3. In the Access Group field, select the group you created
|
||||
4. Save the key
|
||||
|
||||
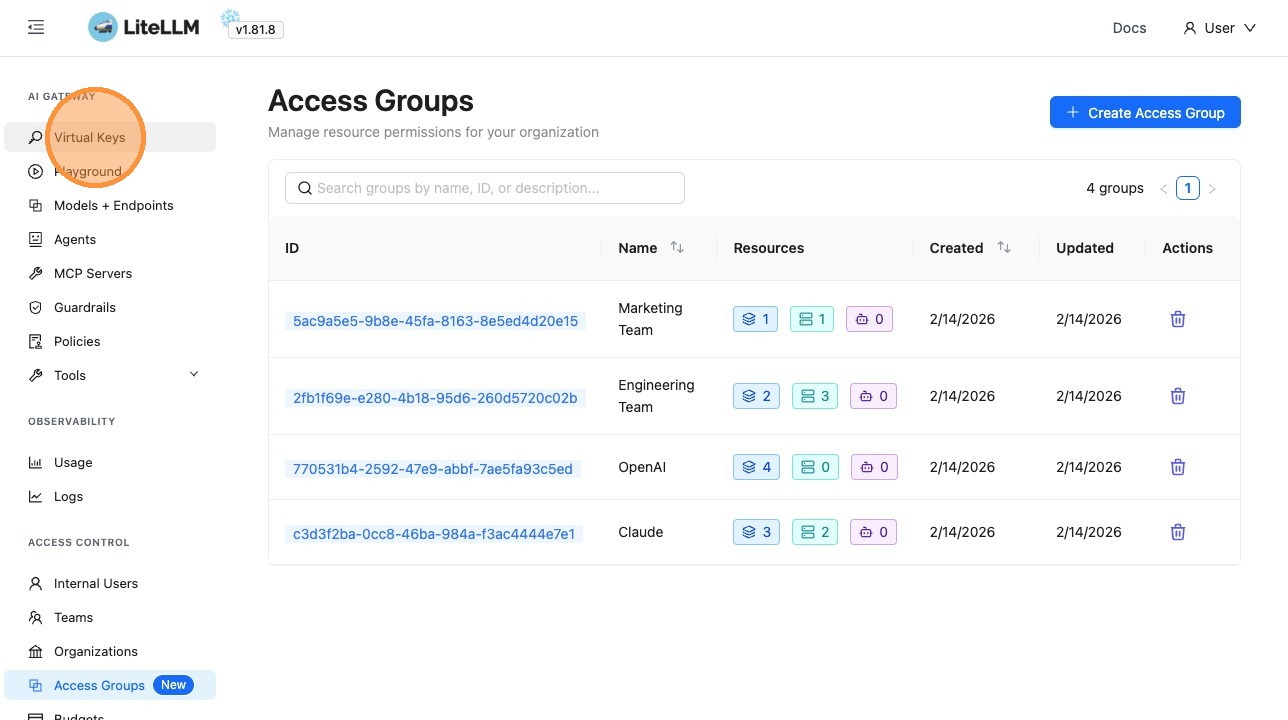
|
||||
|
||||
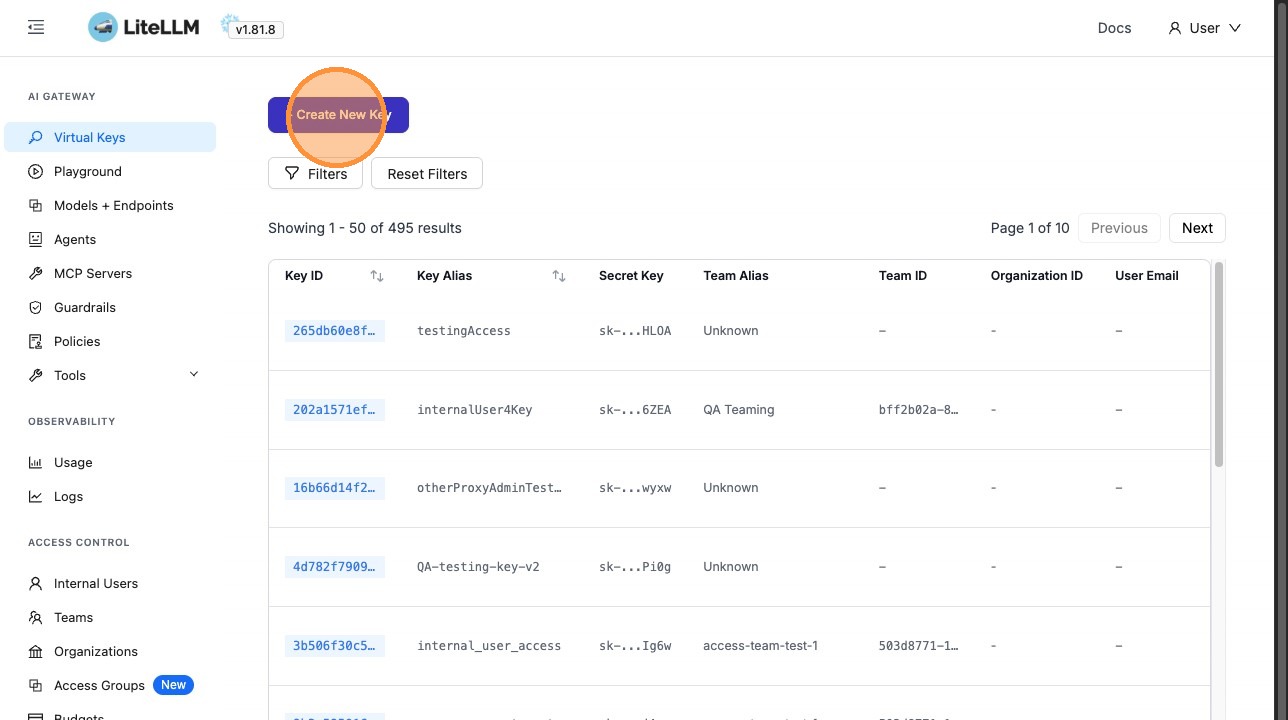
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
### 5. Attach the Access Group to a Team
|
||||
|
||||
You can also attach an Access Group to a team when creating or editing the team. All keys associated with that team will then have access to the resources defined in the group.
|
||||
|
||||
## Use Cases
|
||||
|
||||
### Team-based Access
|
||||
|
||||
Create groups like "Engineering", "Data Science", or "Product" with the models, MCP servers, and agents each team needs. Attach the group to the team—no need to configure each resource on every key.
|
||||
|
||||
### Environment Separation
|
||||
|
||||
- **Production group** – Production models, approved MCP servers, and production agents
|
||||
- **Development group** – Cost-efficient models, experimental MCP tools, and dev agents
|
||||
|
||||
Attach the appropriate group to keys or teams based on environment.
|
||||
|
||||
### Simplified Onboarding
|
||||
|
||||
New developers get a key with an Access Group instead of manually configuring models, MCP servers, and agents. Add them to the right team or give them a key with the correct group.
|
||||
|
||||
### Centralized Updates
|
||||
|
||||
When you add a new model or MCP server to a group, every key and team attached to that group automatically gains access. Remove a resource from the group and it’s revoked everywhere at once.
|
||||
|
||||
## Access Group vs. Model Access Groups
|
||||
|
||||
LiteLLM has two related concepts:
|
||||
|
||||
| Feature | **Access Groups** (this page) | **Model Access Groups** |
|
||||
| ---------- | ----------------------------------------------------------------------- | ------------------------------------------------------- |
|
||||
| Definition | Define in the UI; one group can include models, MCP servers, and agents | Defined in config or via API; groups are model-centric |
|
||||
| Scope | Models + MCP servers + agents | Models only |
|
||||
| Attach to | Keys, teams | Keys, teams |
|
||||
| Use when | You want unified control over models, MCP, and agents from the UI | You need config-based or API-based model access control |
|
||||
|
||||
For config-based model access with `access_groups` in `model_info`, see [Model Access Groups](./model_access_groups.md).
|
||||
|
||||
## Related Documentation
|
||||
|
||||
- [Virtual Keys](./virtual_keys.md) – Creating and managing API keys
|
||||
- [Role-based Access Controls](./access_control.md) – Organizations, teams, and user roles
|
||||
- [Model Access Groups](./model_access_groups.md) – Config-based model access groups
|
||||
- [MCP Control](../mcp_control.md) – MCP server setup and access control
|
||||
|
|
@ -395,7 +395,7 @@ router_settings:
|
|||
| ATHINA_API_KEY | API key for Athina service
|
||||
| ATHINA_BASE_URL | Base URL for Athina service (defaults to `https://log.athina.ai`)
|
||||
| AUTH_STRATEGY | Strategy used for authentication (e.g., OAuth, API key)
|
||||
| AUTO_REDIRECT_UI_LOGIN_TO_SSO | Flag to enable automatic redirect of UI login page to SSO when SSO is configured. Default is **true**
|
||||
| AUTO_REDIRECT_UI_LOGIN_TO_SSO | Flag to enable automatic redirect of UI login page to SSO when SSO is configured. Default is **false**
|
||||
| AUDIO_SPEECH_CHUNK_SIZE | Chunk size for audio speech processing. Default is 1024
|
||||
| ANTHROPIC_API_KEY | API key for Anthropic service
|
||||
| ANTHROPIC_API_BASE | Base URL for Anthropic API. Default is https://api.anthropic.com
|
||||
|
|
@ -520,6 +520,7 @@ router_settings:
|
|||
| DEBUG_OTEL | Enable debug mode for OpenTelemetry
|
||||
| DEFAULT_ALLOWED_FAILS | Maximum failures allowed before cooling down a model. Default is 3
|
||||
| DEFAULT_A2A_AGENT_TIMEOUT | Default timeout in seconds for A2A (Agent-to-Agent) protocol requests. Default is 6000
|
||||
| DEFAULT_ACCESS_GROUP_CACHE_TTL | Time-to-live in seconds for cached access group information. Default is 600 (10 minutes)
|
||||
| DEFAULT_ANTHROPIC_CHAT_MAX_TOKENS | Default maximum tokens for Anthropic chat completions. Default is 4096
|
||||
| DEFAULT_BATCH_SIZE | Default batch size for operations. Default is 512
|
||||
| DEFAULT_CHUNK_OVERLAP | Default chunk overlap for RAG text splitters. Default is 200
|
||||
|
|
@ -548,6 +549,7 @@ router_settings:
|
|||
| DEFAULT_MCP_SEMANTIC_FILTER_EMBEDDING_MODEL | Default embedding model for MCP semantic tool filtering. Default is "text-embedding-3-small"
|
||||
| DEFAULT_MCP_SEMANTIC_FILTER_SIMILARITY_THRESHOLD | Default similarity threshold for MCP semantic tool filtering. Default is 0.3
|
||||
| DEFAULT_MCP_SEMANTIC_FILTER_TOP_K | Default number of top results to return for MCP semantic tool filtering. Default is 10
|
||||
| MCP_NPM_CACHE_DIR | Directory for npm cache used by STDIO MCP servers. In containers the default (~/.npm) may not exist or be read-only. Default is `/tmp/.npm_mcp_cache`
|
||||
| MCP_OAUTH2_TOKEN_CACHE_DEFAULT_TTL | Default TTL in seconds for MCP OAuth2 token cache. Default is 3600
|
||||
| MCP_OAUTH2_TOKEN_CACHE_MAX_SIZE | Maximum number of entries in MCP OAuth2 token cache. Default is 200
|
||||
| MCP_OAUTH2_TOKEN_CACHE_MIN_TTL | Minimum TTL in seconds for MCP OAuth2 token cache. Default is 10
|
||||
|
|
@ -555,7 +557,7 @@ router_settings:
|
|||
| DEFAULT_MOCK_RESPONSE_COMPLETION_TOKEN_COUNT | Default token count for mock response completions. Default is 20
|
||||
| DEFAULT_MOCK_RESPONSE_PROMPT_TOKEN_COUNT | Default token count for mock response prompts. Default is 10
|
||||
| DEFAULT_MODEL_CREATED_AT_TIME | Default creation timestamp for models. Default is 1677610602
|
||||
| DEFAULT_NUM_WORKERS_LITELLM_PROXY | Default number of workers for LiteLLM proxy. Default is 4. **We strongly recommend setting NUM Workers to Number of vCPUs available**
|
||||
| DEFAULT_NUM_WORKERS_LITELLM_PROXY | Default number of workers for LiteLLM proxy when `NUM_WORKERS` is not set. Default is 1. **We strongly recommend setting NUM_WORKERS to the number of vCPUs available** (e.g. `NUM_WORKERS=8` or `--num_workers 8`).
|
||||
| DEFAULT_PROMPT_INJECTION_SIMILARITY_THRESHOLD | Default threshold for prompt injection similarity. Default is 0.7
|
||||
| DEFAULT_POLLING_INTERVAL | Default polling interval for schedulers in seconds. Default is 0.03
|
||||
| DEFAULT_REASONING_EFFORT_DISABLE_THINKING_BUDGET | Default reasoning effort disable thinking budget. Default is 0
|
||||
|
|
@ -745,9 +747,12 @@ router_settings:
|
|||
| LITERAL_API_KEY | API key for Literal integration
|
||||
| LITERAL_API_URL | API URL for Literal service
|
||||
| LITERAL_BATCH_SIZE | Batch size for Literal operations
|
||||
| LITELLM_ANTHROPIC_BETA_HEADERS_URL | Custom URL for fetching Anthropic beta headers configuration. Default is the GitHub main branch URL
|
||||
| LITELLM_ANTHROPIC_DISABLE_URL_SUFFIX | Disable automatic URL suffix appending for Anthropic API base URLs. When set to `true`, prevents LiteLLM from automatically adding `/v1/messages` or `/v1/complete` to custom Anthropic API endpoints
|
||||
| LITELLM_ASSETS_PATH | Path to directory for UI assets and logos. Used when running with read-only filesystem (e.g., Kubernetes). Default is `/var/lib/litellm/assets` in Docker.
|
||||
| LITELLM_CLI_JWT_EXPIRATION_HOURS | Expiration time in hours for CLI-generated JWT tokens. Default is 24 hours
|
||||
| LITELLM_DD_AGENT_HOST | Hostname or IP of DataDog agent for LiteLLM-specific logging. When set, logs are sent to agent instead of direct API
|
||||
| LITELLM_DEPLOYMENT_ENVIRONMENT | Environment name for the deployment (e.g., "production", "staging"). Used as a fallback when OTEL_ENVIRONMENT_NAME is not set. Sets the `environment` tag in telemetry data
|
||||
| LITELLM_DD_AGENT_PORT | Port of DataDog agent for LiteLLM-specific log intake. Default is 10518
|
||||
| LITELLM_DD_LLM_OBS_PORT | Port for Datadog LLM Observability agent. Default is 8126
|
||||
| LITELLM_DONT_SHOW_FEEDBACK_BOX | Flag to hide feedback box in LiteLLM UI
|
||||
|
|
@ -760,11 +765,15 @@ router_settings:
|
|||
| LITELLM_MIGRATION_DIR | Custom migrations directory for prisma migrations, used for baselining db in read-only file systems.
|
||||
| LITELLM_HOSTED_UI | URL of the hosted UI for LiteLLM
|
||||
| LITELLM_UI_API_DOC_BASE_URL | Optional override for the API Reference base URL (used in sample code/docs) when the admin UI runs on a different host than the proxy. Defaults to `PROXY_BASE_URL` when unset.
|
||||
| LITELLM_UI_PATH | Path to directory for Admin UI files. Used when running with read-only filesystem (e.g., Kubernetes). Default is `/var/lib/litellm/ui` in Docker.
|
||||
| LITELM_ENVIRONMENT | Environment of LiteLLM Instance, used by logging services. Currently only used by DeepEval.
|
||||
| LITELLM_KEY_ROTATION_ENABLED | Enable auto-key rotation for LiteLLM (boolean). Default is false.
|
||||
| LITELLM_KEY_ROTATION_CHECK_INTERVAL_SECONDS | Interval in seconds for how often to run job that auto-rotates keys. Default is 86400 (24 hours).
|
||||
| LITELLM_KEY_ROTATION_GRACE_PERIOD | Duration to keep old key valid after rotation (e.g. "24h", "2d"). Default is empty (immediate revoke). Used for scheduled rotations and as fallback when not specified in regenerate request.
|
||||
| LITELLM_LICENSE | License key for LiteLLM usage
|
||||
| LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS | Set to `True` to use the local bundled Anthropic beta headers config only, disabling remote fetching. Default is `False`
|
||||
| LITELLM_LOCAL_MODEL_COST_MAP | Local configuration for model cost mapping in LiteLLM
|
||||
| LITELLM_LOCAL_POLICY_TEMPLATES | When set to "true", uses local backup policy templates instead of fetching from GitHub. Policy templates are fetched from https://raw.githubusercontent.com/BerriAI/litellm/main/policy_templates.json by default, with automatic fallback to local backup on failure
|
||||
| LITELLM_LOG | Enable detailed logging for LiteLLM
|
||||
| LITELLM_MODEL_COST_MAP_URL | URL for fetching model cost map data. Default is https://raw.githubusercontent.com/BerriAI/litellm/main/model_prices_and_context_window.json
|
||||
| LITELLM_LOG_FILE | File path to write LiteLLM logs to. When set, logs will be written to both console and the specified file
|
||||
|
|
@ -772,6 +781,10 @@ router_settings:
|
|||
| LITELLM_METER_NAME | Name for OTEL Meter
|
||||
| LITELLM_OTEL_INTEGRATION_ENABLE_EVENTS | Optionally enable semantic logs for OTEL
|
||||
| LITELLM_OTEL_INTEGRATION_ENABLE_METRICS | Optionally enable emantic metrics for OTEL
|
||||
| LITELLM_ENABLE_PYROSCOPE | If true, enables Pyroscope CPU profiling. Profiles are sent to PYROSCOPE_SERVER_ADDRESS. Off by default. See [Pyroscope profiling](/proxy/pyroscope_profiling).
|
||||
| PYROSCOPE_APP_NAME | Application name reported to Pyroscope. Required when LITELLM_ENABLE_PYROSCOPE is true. No default.
|
||||
| PYROSCOPE_SERVER_ADDRESS | Pyroscope server URL to send profiles to. Required when LITELLM_ENABLE_PYROSCOPE is true. No default.
|
||||
| PYROSCOPE_SAMPLE_RATE | Optional. Sample rate for Pyroscope profiling (integer). No default; when unset, the pyroscope-io library default is used.
|
||||
| LITELLM_MASTER_KEY | Master key for proxy authentication
|
||||
| LITELLM_MODE | Operating mode for LiteLLM (e.g., production, development)
|
||||
| LITELLM_NON_ROOT | Flag to run LiteLLM in non-root mode for enhanced security in Docker containers
|
||||
|
|
@ -784,6 +797,7 @@ router_settings:
|
|||
| LITELLM_USER_AGENT | Custom user agent string for LiteLLM API requests. Used for partner telemetry attribution
|
||||
| LITELLM_PRINT_STANDARD_LOGGING_PAYLOAD | If true, prints the standard logging payload to the console - useful for debugging
|
||||
| LITELM_ENVIRONMENT | Environment for LiteLLM Instance. This is currently only logged to DeepEval to determine the environment for DeepEval integration.
|
||||
| LITELLM_ASYNCIO_QUEUE_MAXSIZE | Maximum size for asyncio queues (e.g. log queues, spend update queues, and cookbook examples such as realtime audio in `nova_sonic_realtime.py`). Bounds in-memory growth to prevent OOM. Default is 1000.
|
||||
| LOGFIRE_TOKEN | Token for Logfire logging service
|
||||
| LOGFIRE_BASE_URL | Base URL for Logfire logging service (useful for self hosted deployments)
|
||||
| LOGGING_WORKER_CONCURRENCY | Maximum number of concurrent coroutine slots for the logging worker on the asyncio event loop. Default is 100. Setting too high will flood the event loop with logging tasks which will lower the overall latency of the requests.
|
||||
|
|
@ -811,6 +825,7 @@ router_settings:
|
|||
| MAX_RETRY_DELAY | Maximum delay in seconds for retrying requests. Default is 8.0
|
||||
| MAX_LANGFUSE_INITIALIZED_CLIENTS | Maximum number of Langfuse clients to initialize on proxy. Default is 50. This is set since langfuse initializes 1 thread everytime a client is initialized. We've had an incident in the past where we reached 100% cpu utilization because Langfuse was initialized several times.
|
||||
| MAX_MCP_SEMANTIC_FILTER_TOOLS_HEADER_LENGTH | Maximum header length for MCP semantic filter tools. Default is 150
|
||||
| MAX_POLICY_ESTIMATE_IMPACT_ROWS | Maximum number of rows returned when estimating the impact of a policy. Default is 1000
|
||||
| MIN_NON_ZERO_TEMPERATURE | Minimum non-zero temperature value. Default is 0.0001
|
||||
| MINIMUM_PROMPT_CACHE_TOKEN_COUNT | Minimum token count for caching a prompt. Default is 1024
|
||||
| MISTRAL_API_BASE | Base URL for Mistral API. Default is https://api.mistral.ai
|
||||
|
|
@ -827,6 +842,8 @@ router_settings:
|
|||
| MICROSOFT_USER_ID_ATTRIBUTE | Field name for user ID in Microsoft SSO response. Default is `id`
|
||||
| MICROSOFT_USER_LAST_NAME_ATTRIBUTE | Field name for user last name in Microsoft SSO response. Default is `surname`
|
||||
| MICROSOFT_USERINFO_ENDPOINT | Custom userinfo endpoint URL for Microsoft SSO (overrides default Microsoft Graph userinfo endpoint)
|
||||
| MODEL_COST_MAP_MAX_SHRINK_RATIO | Maximum allowed shrinkage ratio when validating a fetched model cost map against the local backup. Rejects the fetched map if it is smaller than this fraction of the backup. Default is 0.5
|
||||
| MODEL_COST_MAP_MIN_MODEL_COUNT | Minimum number of models a fetched cost map must contain to be considered valid. Default is 50
|
||||
| NO_DOCS | Flag to disable Swagger UI documentation
|
||||
| NO_REDOC | Flag to disable Redoc documentation
|
||||
| NO_PROXY | List of addresses to bypass proxy
|
||||
|
|
|
|||
|
|
@ -469,6 +469,7 @@ credential_list:
|
|||
api_version: "2023-05-15"
|
||||
credential_info:
|
||||
description: "Production credentials for EU region"
|
||||
custom_llm_provider: "azure"
|
||||
```
|
||||
|
||||
#### Key Parameters
|
||||
|
|
|
|||
|
|
@ -1,3 +1,7 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# [Beta] Guardrail Policies
|
||||
|
||||
Use policies to group guardrails and control which ones run for specific teams, keys, or models.
|
||||
|
|
@ -10,6 +14,9 @@ Use policies to group guardrails and control which ones run for specific teams,
|
|||
|
||||
## Quick Start
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="config" label="config.yaml">
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
|
|
@ -43,6 +50,26 @@ policy_attachments:
|
|||
scope: "*" # apply to all requests
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="ui" label="UI (LiteLLM Dashboard)">
|
||||
|
||||
**Step 1: Create a Policy**
|
||||
|
||||
Go to **Policies** tab and click **+ Create New Policy**. Fill in the policy name, description, and select guardrails to add.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
Response headers show what ran:
|
||||
|
||||
```
|
||||
|
|
@ -58,6 +85,9 @@ x-litellm-applied-guardrails: pii_masking,prompt_injection
|
|||
|
||||
You have a global baseline, but want to add extra guardrails for a specific team.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="config" label="config.yaml">
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
policies:
|
||||
global-baseline:
|
||||
|
|
@ -81,6 +111,30 @@ policy_attachments:
|
|||
- finance # team alias from /team/new
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="ui" label="UI (LiteLLM Dashboard)">
|
||||
|
||||
**Option 1: Create a team-scoped attachment**
|
||||
|
||||
Go to **Policies** > **Attachments** tab and click **+ Create New Attachment**. Select the policy and the teams to scope it to.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
**Option 2: Attach from team settings**
|
||||
|
||||
Go to **Teams** > click on a team > **Settings** tab > under **Policies**, select the policies to attach.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
<Image img={require('../../../img/policy_team_attach.png')} />
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
Now the `finance` team gets `pii_masking` + `strict_compliance_check` + `audit_logger`, while everyone else just gets `pii_masking`.
|
||||
|
||||
## Remove guardrails for a specific team
|
||||
|
|
@ -201,6 +255,60 @@ policy_attachments:
|
|||
- "test-*" # key alias pattern
|
||||
```
|
||||
|
||||
**Tag-based** (matches keys/teams by metadata tags, wildcards supported):
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
policy_attachments:
|
||||
- policy: hipaa-compliance
|
||||
tags:
|
||||
- "healthcare"
|
||||
- "health-*" # wildcard - matches health-team, health-dev, etc.
|
||||
```
|
||||
|
||||
Tags are read from key and team `metadata.tags`. For example, a key created with `metadata: {"tags": ["healthcare"]}` would match the attachment above.
|
||||
|
||||
## Test Policy Matching
|
||||
|
||||
Debug which policies and guardrails apply for a given context. Use this to verify your policy configuration before deploying.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI (LiteLLM Dashboard)">
|
||||
|
||||
Go to **Policies** > **Test** tab. Enter a team alias, key alias, model, or tags and click **Test** to see which policies match and what guardrails would be applied.
|
||||
|
||||
<Image img={require('../../../img/policy_test_matching.png')} />
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
```bash
|
||||
curl -X POST "http://localhost:4000/policies/resolve" \
|
||||
-H "Authorization: Bearer <your_api_key>" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"tags": ["healthcare"],
|
||||
"model": "gpt-4"
|
||||
}'
|
||||
```
|
||||
|
||||
Response:
|
||||
|
||||
```json
|
||||
{
|
||||
"effective_guardrails": ["pii_masking"],
|
||||
"matched_policies": [
|
||||
{
|
||||
"policy_name": "hipaa-compliance",
|
||||
"matched_via": "tag:healthcare",
|
||||
"guardrails_added": ["pii_masking"]
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Config Reference
|
||||
|
||||
### `policies`
|
||||
|
|
@ -233,14 +341,18 @@ policy_attachments:
|
|||
scope: ...
|
||||
teams: [...]
|
||||
keys: [...]
|
||||
models: [...]
|
||||
tags: [...]
|
||||
```
|
||||
|
||||
| Field | Type | Description |
|
||||
|-------|------|-------------|
|
||||
| `policy` | `string` | **Required.** Name of the policy to attach. |
|
||||
| `scope` | `string` | Use `"*"` to apply globally. |
|
||||
| `teams` | `list[string]` | Team aliases (from `/team/new`). |
|
||||
| `teams` | `list[string]` | Team aliases (from `/team/new`). Supports `*` wildcard. |
|
||||
| `keys` | `list[string]` | Key aliases (from `/key/generate`). Supports `*` wildcard. |
|
||||
| `models` | `list[string]` | Model names. Supports `*` wildcard. |
|
||||
| `tags` | `list[string]` | Tag patterns (from key/team `metadata.tags`). Supports `*` wildcard. |
|
||||
|
||||
### Response Headers
|
||||
|
||||
|
|
@ -248,6 +360,7 @@ policy_attachments:
|
|||
|--------|-------------|
|
||||
| `x-litellm-applied-policies` | Policies that matched this request |
|
||||
| `x-litellm-applied-guardrails` | Guardrails that actually ran |
|
||||
| `x-litellm-policy-sources` | Why each policy matched (e.g., `hipaa=tag:healthcare; baseline=scope:*`) |
|
||||
|
||||
## How it works
|
||||
|
||||
|
|
|
|||
139
docs/my-website/docs/proxy/guardrails/policy_tags.md
Normal file
139
docs/my-website/docs/proxy/guardrails/policy_tags.md
Normal file
|
|
@ -0,0 +1,139 @@
|
|||
# Tag-Based Policy Attachments
|
||||
|
||||
Apply guardrail policies automatically to any key or team that has a specific tag. Instead of attaching policies one-by-one, tag your keys and let the policy engine handle the rest.
|
||||
|
||||
**Example:** Your security team requires all healthcare-related keys to run PII masking and PHI detection. Tag those keys with `health`, create a single tag-based attachment, and every matching key gets the guardrails automatically.
|
||||
|
||||
## 1. Create a Policy with Guardrails
|
||||
|
||||
Navigate to **Policies** in the left sidebar. You'll see a list of existing policies along with their guardrails.
|
||||
|
||||
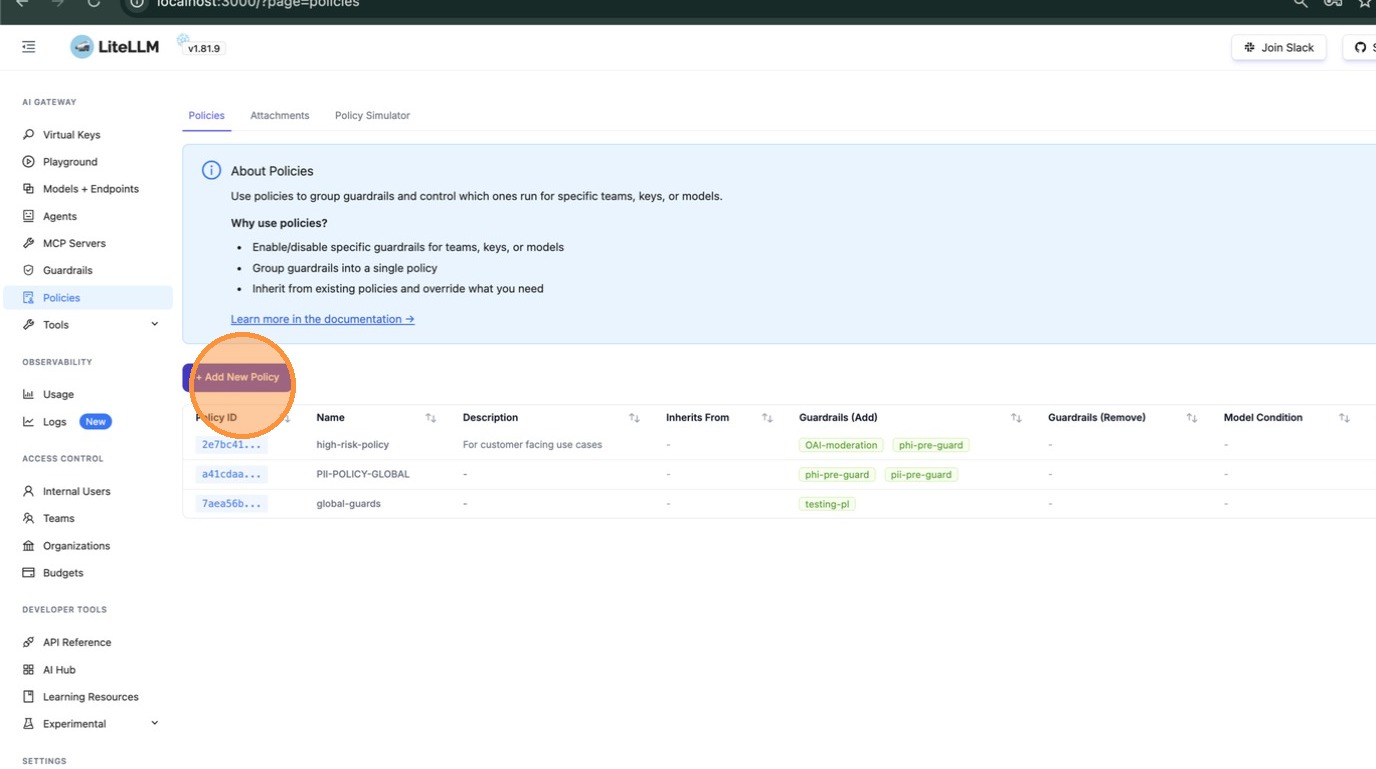
|
||||
|
||||
Click **+ Add New Policy**. In the modal, enter a name for your policy (e.g., `high-risk-policy2`). You can also type to search existing policy names if you want to reference them.
|
||||
|
||||
|
||||
|
||||
Scroll down to **Guardrails to Add**. Click the dropdown to see all available guardrails configured on your proxy — select the ones this policy should enforce.
|
||||
|
||||
|
||||
|
||||
After selecting your guardrails, they appear as chips in the input field. The **Resolved Guardrails** section below shows the final set that will be applied (including any inherited from a parent policy).
|
||||
|
||||
|
||||
|
||||
Click **Create Policy** to save.
|
||||
|
||||
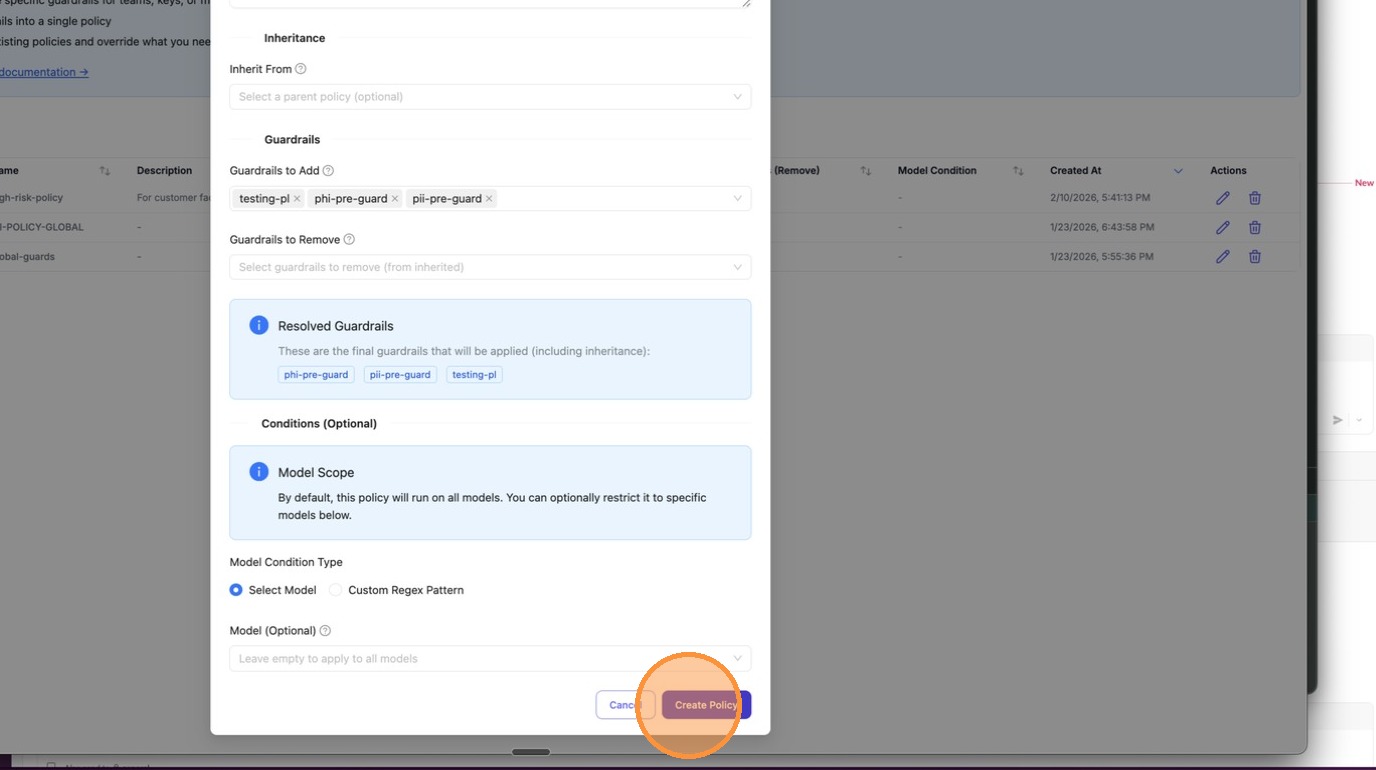
|
||||
|
||||
## 2. Add a Tag Attachment for the Policy
|
||||
|
||||
After creating the policy, switch to the **Attachments** tab. This is where you define *where* the policy applies.
|
||||
|
||||
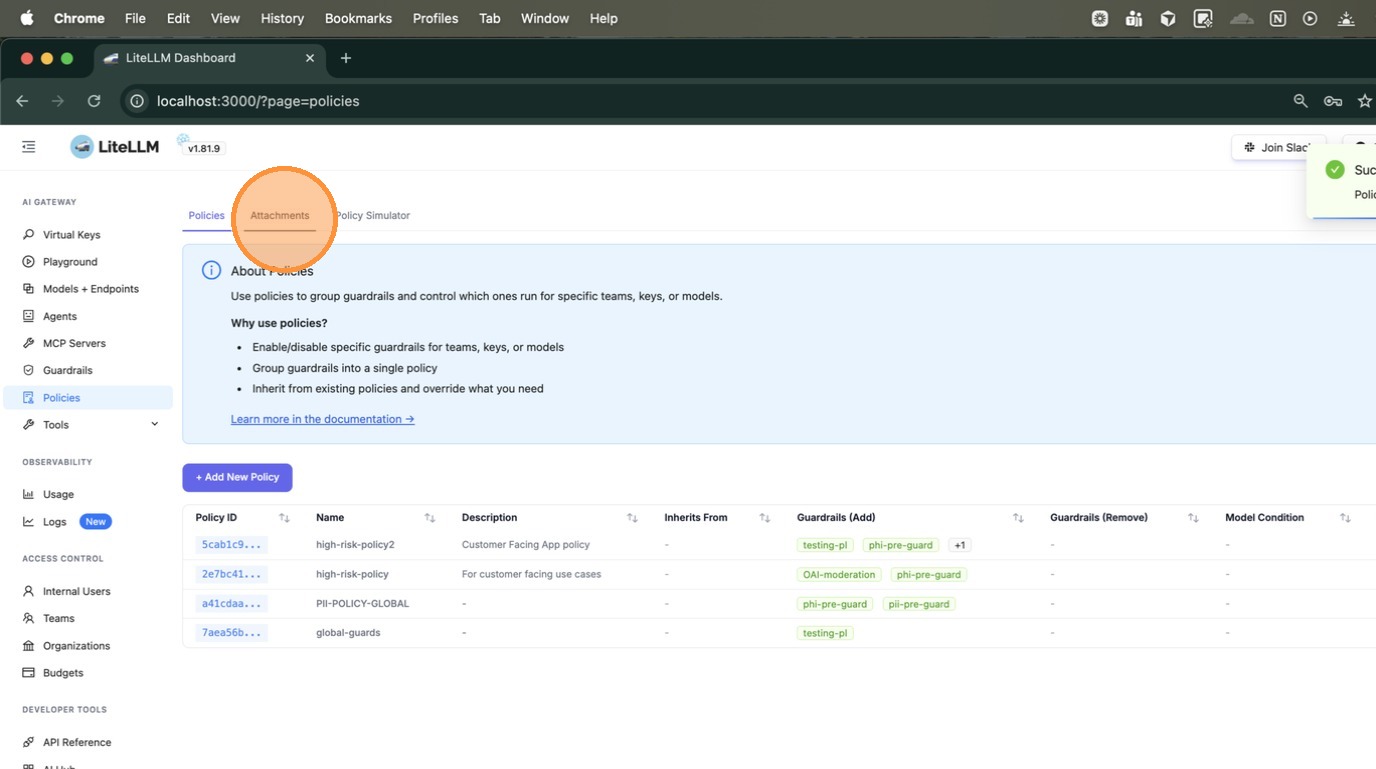
|
||||
|
||||
Click **+ Add New Attachment**. The Attachments page explains the available scopes: Global, Teams, Keys, Models, and **Tags**.
|
||||
|
||||
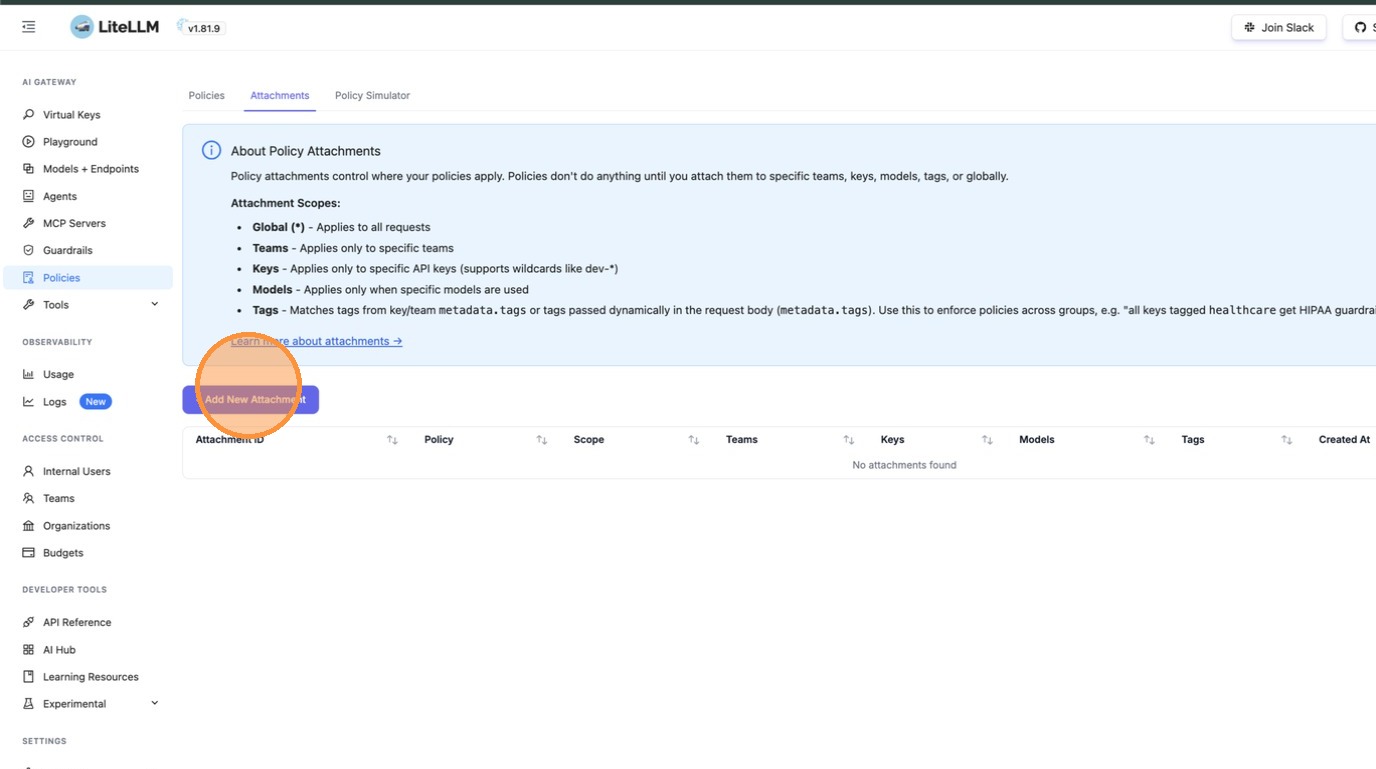
|
||||
|
||||
In the **Create Policy Attachment** modal, first select the policy you just created from the dropdown.
|
||||
|
||||
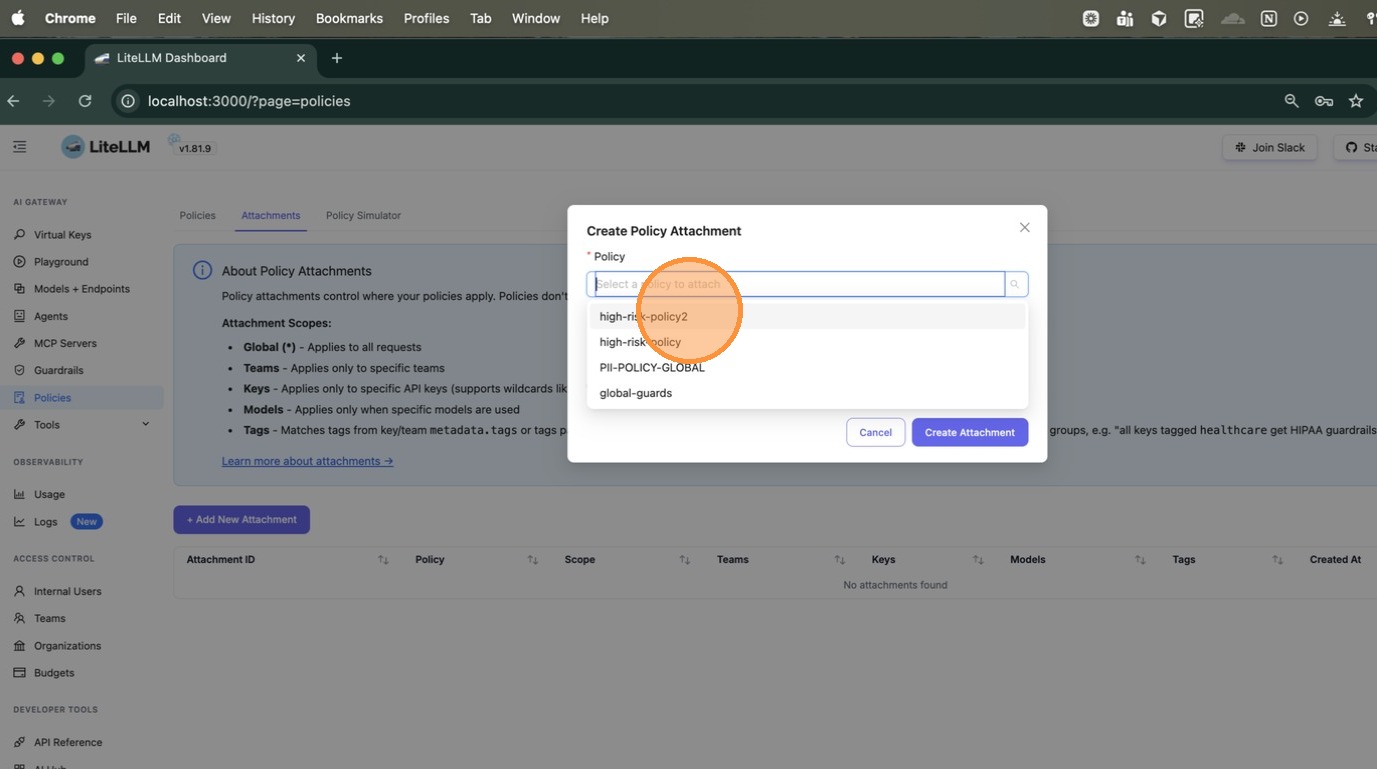
|
||||
|
||||
Choose **Specific (teams, keys, models, or tags)** as the scope type. This expands the form to show fields for Teams, Keys, Models, and Tags.
|
||||
|
||||
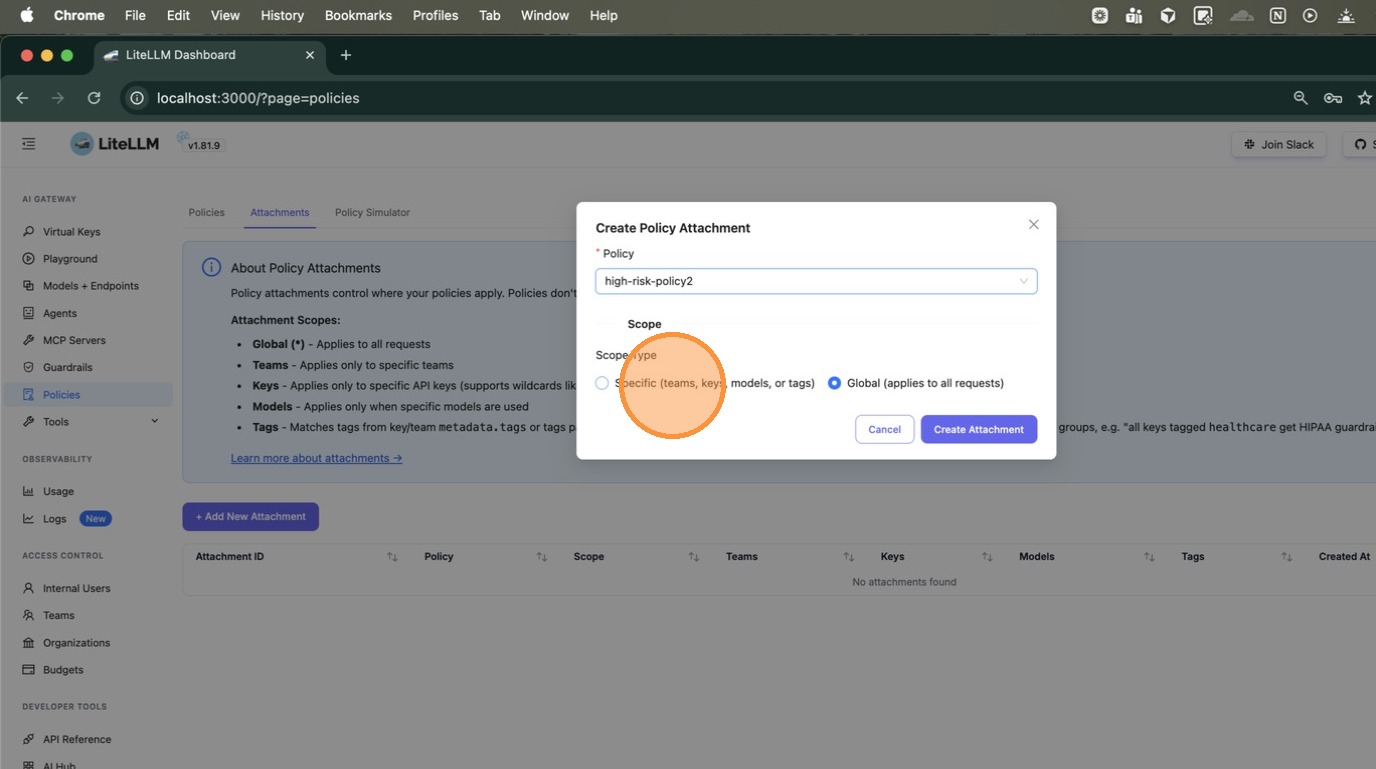
|
||||
|
||||
Scroll down to the **Tags** field and type the tag to match — here we enter `health`. You can enter any string, or use a wildcard pattern like `health-*` to match all tags starting with `health-` (e.g., `health-team`, `health-dev`).
|
||||
|
||||
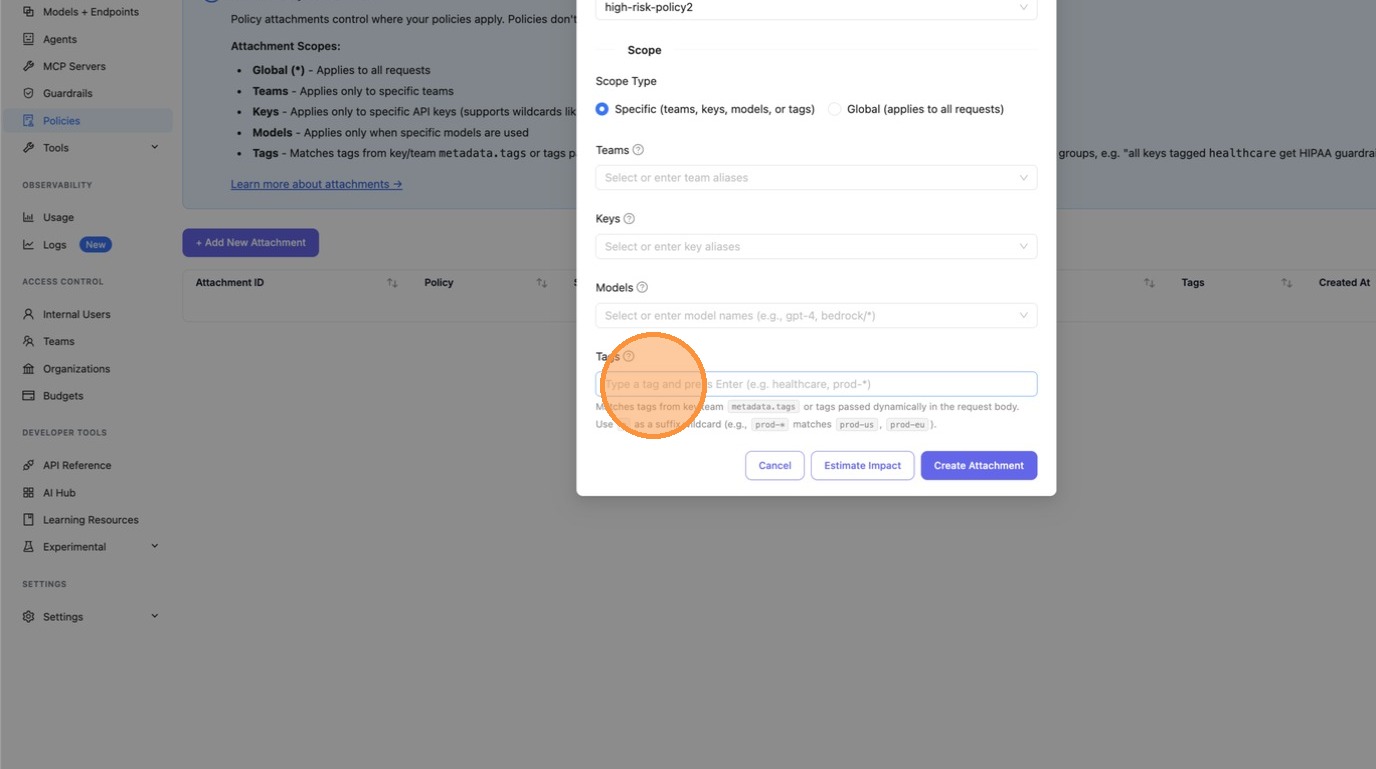
|
||||
|
||||
## 3. Check the Impact of the Attachment
|
||||
|
||||
Before creating the attachment, click **Estimate Impact** to preview how many keys and teams would be affected. This is your blast-radius check — make sure the scope is what you expect before applying.
|
||||
|
||||
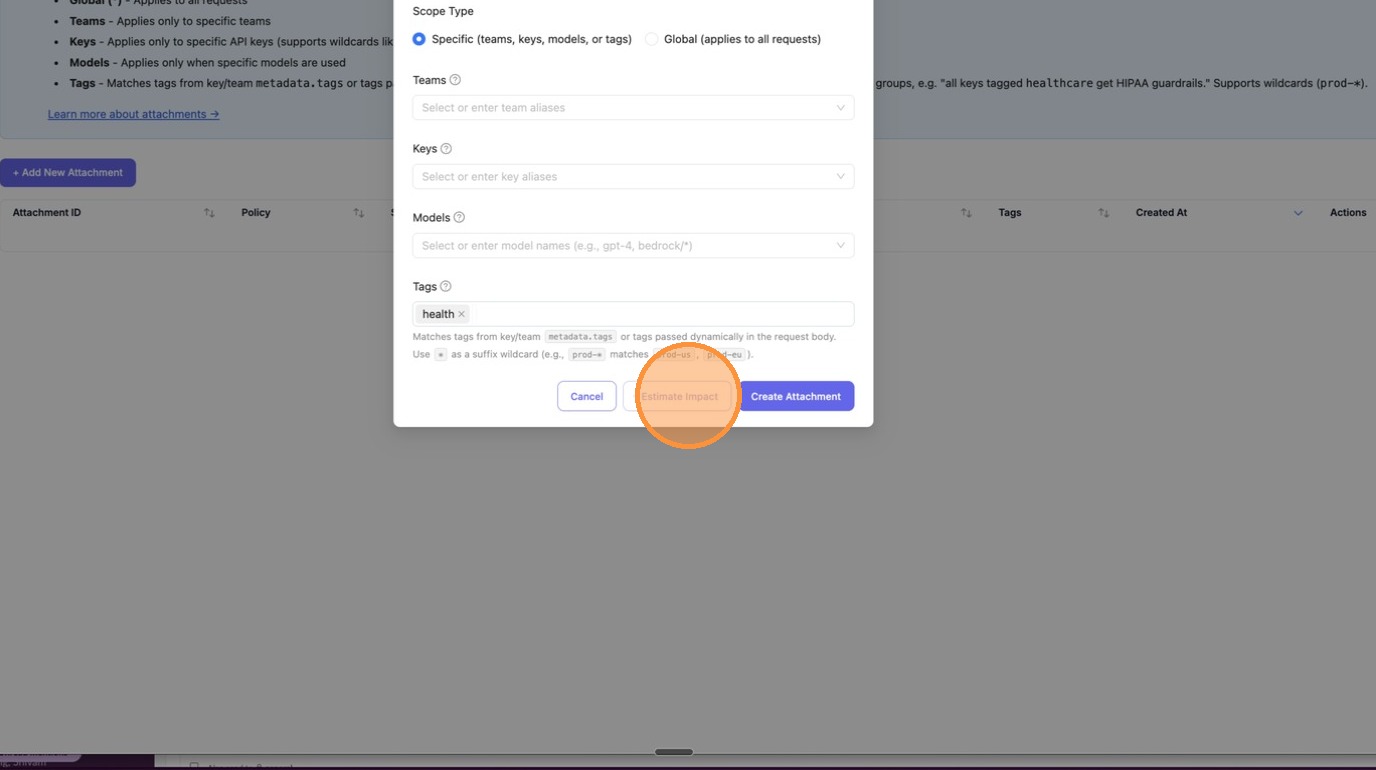
|
||||
|
||||
The **Impact Preview** appears inline, showing exactly how many keys and teams would be affected. In this example: "This attachment would affect **1 key** and **0 teams**", with the key alias `hi` listed.
|
||||
|
||||
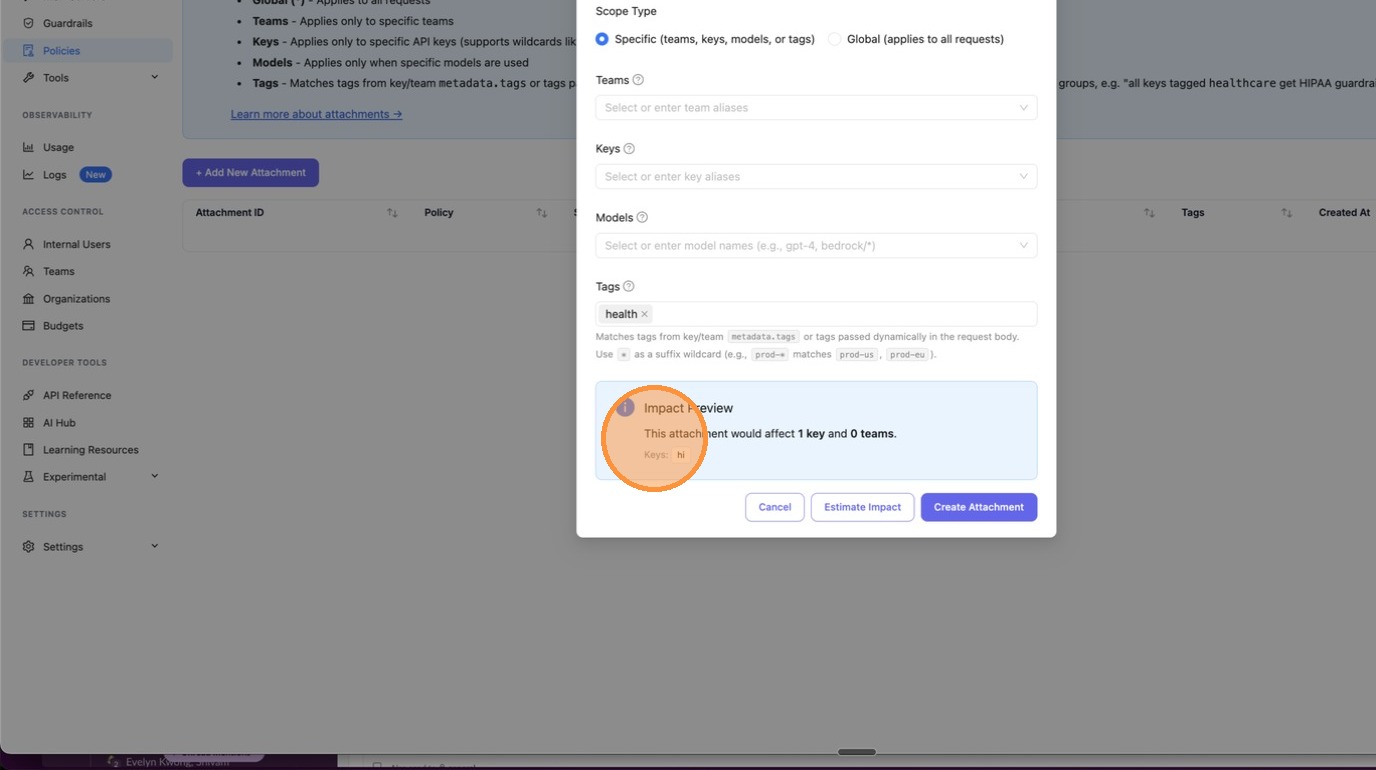
|
||||
|
||||
Once you're satisfied with the impact, click **Create Attachment** to save.
|
||||
|
||||
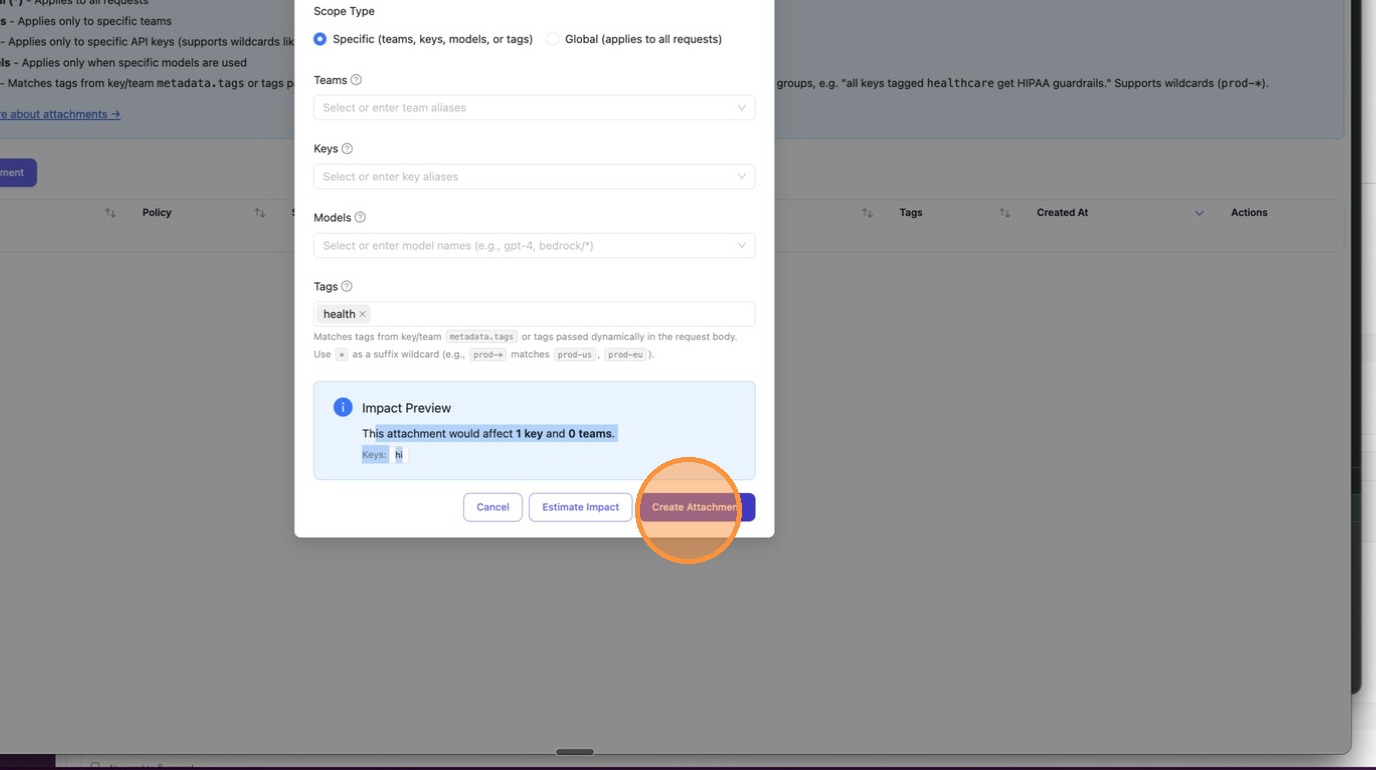
|
||||
|
||||
The attachment now appears in the table with the policy name `high-risk-policy2` and tag `health` visible.
|
||||
|
||||
|
||||
|
||||
## 4. Create a Key with the Tag
|
||||
|
||||
Navigate to **Virtual Keys** in the left sidebar. Click **+ Create New Key**.
|
||||
|
||||
|
||||
|
||||
Enter a key name and select a model. Then expand **Optional Settings** and scroll down to the **Tags** field.
|
||||
|
||||
|
||||
|
||||
In the **Tags** field, type `health` and press Enter. This is the tag the policy engine will match against.
|
||||
|
||||
|
||||
|
||||
The tag `health` now appears as a chip in the Tags field. Confirm your settings look correct.
|
||||
|
||||
|
||||
|
||||
Click **Create Key** at the bottom of the form.
|
||||
|
||||
|
||||
|
||||
A dialog appears with your new virtual key. Click **Copy Virtual Key** — you'll need this to test in the next step.
|
||||
|
||||
|
||||
|
||||
## 5. Test the Key and Validate the Policy is Applied
|
||||
|
||||
Navigate to **Playground** in the left sidebar to test the key interactively.
|
||||
|
||||
|
||||
|
||||
Under **Virtual Key Source**, select "Virtual Key" and paste the key you just copied into the input field.
|
||||
|
||||
|
||||
|
||||
Select a model from the **Select Model** dropdown.
|
||||
|
||||
|
||||
|
||||
Type a message and press Enter. If a guardrail blocks the request, you'll see it in the response. In this example, the `testing-pl` guardrail detected an email pattern and returned a 403 error — confirming the policy is working.
|
||||
|
||||
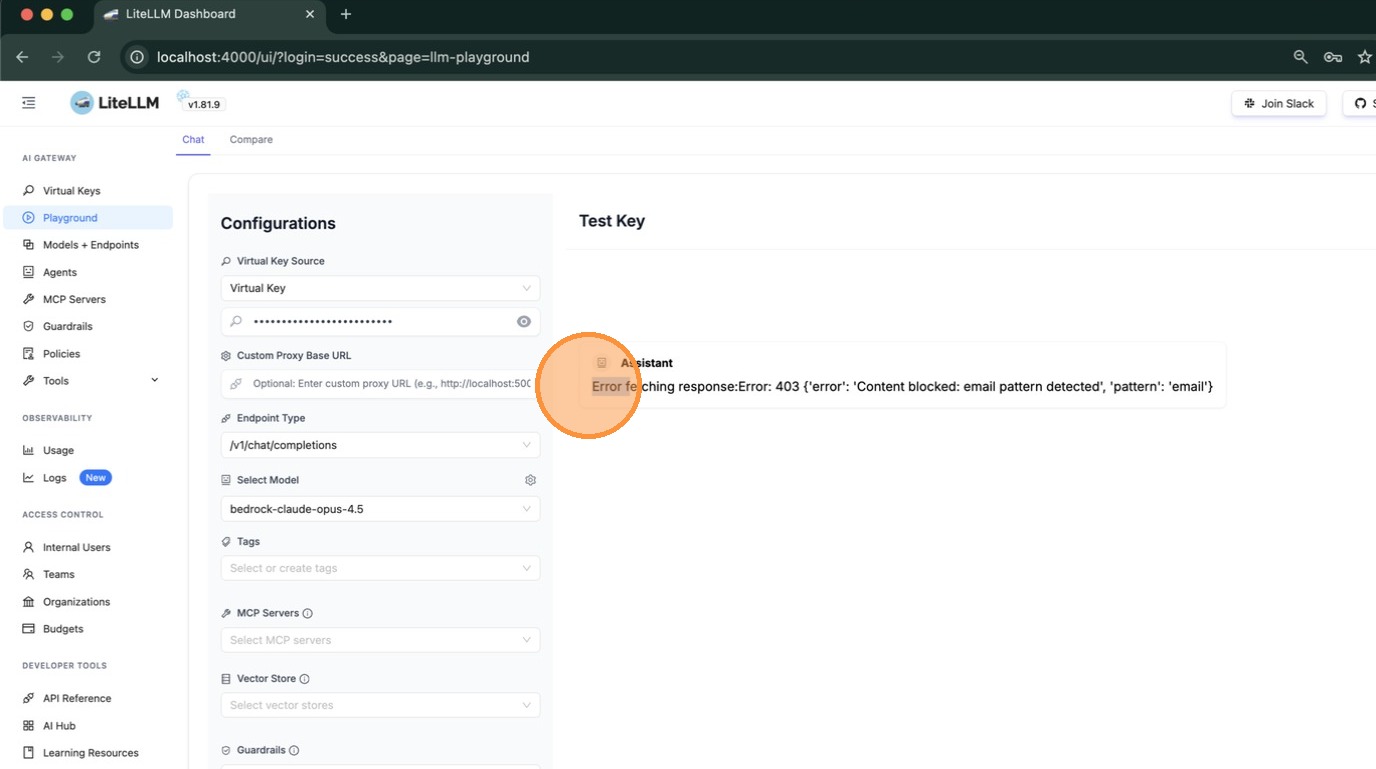
|
||||
|
||||
**Using curl:**
|
||||
|
||||
You can also verify via the command line. The response headers confirm which policies and guardrails were applied:
|
||||
|
||||
```bash
|
||||
curl -v http://localhost:4000/chat/completions \
|
||||
-H "Authorization: Bearer <your-tagged-key>" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "gpt-4o",
|
||||
"messages": [{"role": "user", "content": "say hi"}]
|
||||
}'
|
||||
```
|
||||
|
||||
Check the response headers:
|
||||
|
||||
```
|
||||
x-litellm-applied-policies: high-risk-policy2
|
||||
x-litellm-applied-guardrails: pii-pre-guard,phi-pre-guard,testing-pl
|
||||
x-litellm-policy-sources: high-risk-policy2=tag:health
|
||||
```
|
||||
|
||||
| Header | What it tells you |
|
||||
|--------|-------------------|
|
||||
| `x-litellm-applied-policies` | Which policies matched this request |
|
||||
| `x-litellm-applied-guardrails` | Which guardrails actually ran |
|
||||
| `x-litellm-policy-sources` | **Why** each policy matched — `tag:health` confirms it was the tag |
|
||||
296
docs/my-website/docs/proxy/guardrails/policy_templates.md
Normal file
296
docs/my-website/docs/proxy/guardrails/policy_templates.md
Normal file
|
|
@ -0,0 +1,296 @@
|
|||
# Policy Templates
|
||||
|
||||
Policy templates provide pre-configured guardrail policies that you can use as a starting point for your organization. Instead of manually creating policies and guardrails, you can select a template that matches your use case and deploy it with one click.
|
||||
|
||||
## Using Policy Templates
|
||||
|
||||
### In the UI
|
||||
|
||||
1. Navigate to **Policies → Templates** tab in the LiteLLM Admin UI
|
||||
2. Browse available templates (e.g., "PII Protection", "Cost Control", "HR Compliance")
|
||||
3. Click **"Use Template"** on any template
|
||||
4. Review the guardrails that will be created:
|
||||
- Existing guardrails are marked with a green checkmark
|
||||
- New guardrails can be selected/deselected
|
||||
5. Click **"Create X Guardrails & Use Template"**
|
||||
6. Review and customize the pre-filled policy form
|
||||
7. Click **"Create Policy"** to save
|
||||
|
||||
### Workflow
|
||||
|
||||
```
|
||||
Select Template → Review Guardrails → Create Selected → Edit Policy → Save
|
||||
```
|
||||
|
||||
The system automatically:
|
||||
- ✅ Detects which guardrails already exist
|
||||
- ✅ Creates only the missing guardrails you select
|
||||
- ✅ Pre-fills the policy form with template data
|
||||
- ✅ Lets you customize before saving
|
||||
|
||||
## Available Templates
|
||||
|
||||
Templates are fetched from [GitHub](https://raw.githubusercontent.com/BerriAI/litellm/main/policy_templates.json) with automatic fallback to local backup.
|
||||
|
||||
### Current Templates
|
||||
|
||||
#### 1. Advanced PII Protection (Australia)
|
||||
- **Complexity:** High
|
||||
- **Use Case:** Comprehensive PII detection for Australian organizations
|
||||
- **Guardrails:**
|
||||
- Australian tax identifiers (TFN, ABN, Medicare)
|
||||
- Australian passports
|
||||
- International PII (SSN, passports, national IDs)
|
||||
- Contact information (email, phone, address)
|
||||
- Financial data (credit cards, IBAN)
|
||||
- API credentials (AWS, GitHub, Slack) - **BLOCKS** requests
|
||||
- Network infrastructure (IP addresses)
|
||||
- Protected class information (gender, race, religion, disability, etc.)
|
||||
|
||||
#### 2. Baseline PII Protection
|
||||
- **Complexity:** Low
|
||||
- **Use Case:** Basic protection for internal tools and testing
|
||||
- **Guardrails:**
|
||||
- Australian tax identifiers
|
||||
- API credentials
|
||||
- Financial data
|
||||
|
||||
## Creating Your Own Policy Templates
|
||||
|
||||
You can contribute policy templates for the entire LiteLLM community to use.
|
||||
|
||||
### Template Structure
|
||||
|
||||
Templates are defined in JSON format with the following structure:
|
||||
|
||||
```json
|
||||
{
|
||||
"id": "unique-template-id",
|
||||
"title": "Display Title",
|
||||
"description": "Detailed description of what this template protects",
|
||||
"icon": "ShieldCheckIcon",
|
||||
"iconColor": "text-purple-500",
|
||||
"iconBg": "bg-purple-50",
|
||||
"guardrails": [
|
||||
"guardrail-name-1",
|
||||
"guardrail-name-2"
|
||||
],
|
||||
"complexity": "Low|Medium|High",
|
||||
"guardrailDefinitions": [
|
||||
{
|
||||
"guardrail_name": "example-guardrail",
|
||||
"litellm_params": {
|
||||
"guardrail": "litellm_content_filter",
|
||||
"mode": "pre_call",
|
||||
"patterns": [
|
||||
{
|
||||
"pattern_type": "prebuilt",
|
||||
"pattern_name": "email",
|
||||
"action": "MASK"
|
||||
}
|
||||
],
|
||||
"pattern_redaction_format": "[{pattern_name}_REDACTED]"
|
||||
},
|
||||
"guardrail_info": {
|
||||
"description": "What this guardrail does"
|
||||
}
|
||||
}
|
||||
],
|
||||
"templateData": {
|
||||
"policy_name": "policy-name",
|
||||
"description": "Policy description",
|
||||
"guardrails_add": ["guardrail-name-1", "guardrail-name-2"],
|
||||
"guardrails_remove": []
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Field Descriptions
|
||||
|
||||
#### Display Fields
|
||||
- **id**: Unique identifier (lowercase with hyphens)
|
||||
- **title**: User-facing name shown in UI
|
||||
- **description**: Detailed explanation of what the template protects
|
||||
- **icon**: Icon name (must be available in UI icon map)
|
||||
- **iconColor**: Tailwind CSS text color class
|
||||
- **iconBg**: Tailwind CSS background color class
|
||||
- **guardrails**: Array of guardrail names (for display only)
|
||||
- **complexity**: Badge showing difficulty ("Low", "Medium", or "High")
|
||||
|
||||
#### Guardrail Definitions
|
||||
- **guardrailDefinitions**: Array of complete guardrail configurations
|
||||
- Each must be a valid guardrail object that can be sent to `/guardrails` POST endpoint
|
||||
- If a guardrail already exists, it will be skipped
|
||||
- Can be empty `[]` if template uses only existing guardrails
|
||||
|
||||
#### Policy Configuration
|
||||
- **templateData**: Object that pre-fills the policy form
|
||||
- **policy_name**: Suggested name (user can edit)
|
||||
- **description**: Policy description
|
||||
- **guardrails_add**: Array of guardrail names to include
|
||||
- **guardrails_remove**: Array to remove (usually `[]` for templates)
|
||||
- **inherit**: (Optional) Parent policy name for inheritance
|
||||
|
||||
### Example Template
|
||||
|
||||
Here's a complete example for a HIPAA compliance template:
|
||||
|
||||
```json
|
||||
{
|
||||
"id": "hipaa-compliance",
|
||||
"title": "HIPAA Compliance Policy",
|
||||
"description": "Healthcare compliance policy that masks PHI and enforces HIPAA regulations for healthcare applications.",
|
||||
"icon": "ShieldCheckIcon",
|
||||
"iconColor": "text-red-500",
|
||||
"iconBg": "bg-red-50",
|
||||
"guardrails": [
|
||||
"phi-detector",
|
||||
"medical-record-blocker",
|
||||
"patient-id-masker"
|
||||
],
|
||||
"complexity": "High",
|
||||
"guardrailDefinitions": [
|
||||
{
|
||||
"guardrail_name": "phi-detector",
|
||||
"litellm_params": {
|
||||
"guardrail": "litellm_content_filter",
|
||||
"mode": "pre_call",
|
||||
"patterns": [
|
||||
{
|
||||
"pattern_type": "prebuilt",
|
||||
"pattern_name": "us_ssn",
|
||||
"action": "MASK"
|
||||
},
|
||||
{
|
||||
"pattern_type": "prebuilt",
|
||||
"pattern_name": "email",
|
||||
"action": "MASK"
|
||||
},
|
||||
{
|
||||
"pattern_type": "prebuilt",
|
||||
"pattern_name": "us_phone",
|
||||
"action": "MASK"
|
||||
}
|
||||
],
|
||||
"pattern_redaction_format": "[PHI_REDACTED]"
|
||||
},
|
||||
"guardrail_info": {
|
||||
"description": "Detects and masks Protected Health Information (PHI)"
|
||||
}
|
||||
}
|
||||
],
|
||||
"templateData": {
|
||||
"policy_name": "hipaa-compliance-policy",
|
||||
"description": "HIPAA compliance policy for healthcare applications",
|
||||
"guardrails_add": [
|
||||
"phi-detector",
|
||||
"medical-record-blocker",
|
||||
"patient-id-masker"
|
||||
],
|
||||
"guardrails_remove": []
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## Contributing Templates
|
||||
|
||||
To contribute a policy template for everyone to use:
|
||||
|
||||
### Step 1: Create Your Template JSON
|
||||
|
||||
1. Create a JSON file following the structure above
|
||||
2. Test it locally by adding it to your local `policy_templates.json`
|
||||
3. Verify all guardrails work correctly
|
||||
4. Ensure descriptions are clear and helpful
|
||||
|
||||
### Step 2: Submit a Pull Request
|
||||
|
||||
1. Fork the [LiteLLM repository](https://github.com/BerriAI/litellm)
|
||||
2. Add your template to `policy_templates.json` at the root
|
||||
3. Add your template to `litellm/policy_templates_backup.json` (keep both in sync)
|
||||
4. Create a pull request with:
|
||||
- Clear description of what the template protects
|
||||
- Use case examples
|
||||
- Any relevant compliance frameworks (HIPAA, GDPR, SOC 2, etc.)
|
||||
|
||||
### Guidelines
|
||||
|
||||
**DO:**
|
||||
- ✅ Use clear, descriptive names
|
||||
- ✅ Include comprehensive descriptions
|
||||
- ✅ Test all guardrails thoroughly
|
||||
- ✅ Document pattern sources (e.g., "Based on NIST guidelines")
|
||||
- ✅ Group related guardrails logically
|
||||
- ✅ Consider different complexity levels
|
||||
|
||||
**DON'T:**
|
||||
- ❌ Include credentials or secrets
|
||||
- ❌ Use overly broad patterns that may have false positives
|
||||
- ❌ Duplicate existing templates
|
||||
- ❌ Use custom code without thorough testing
|
||||
|
||||
## Using Templates Offline
|
||||
|
||||
For air-gapped or offline deployments, set the environment variable:
|
||||
|
||||
```bash
|
||||
export LITELLM_LOCAL_POLICY_TEMPLATES=true
|
||||
```
|
||||
|
||||
This forces the system to use the local backup (`litellm/policy_templates_backup.json`) instead of fetching from GitHub.
|
||||
|
||||
## Template Sources
|
||||
|
||||
- **GitHub (default):** https://raw.githubusercontent.com/BerriAI/litellm/main/policy_templates.json
|
||||
- **Local backup:** `litellm/policy_templates_backup.json`
|
||||
|
||||
Templates are automatically fetched from GitHub on each request, with fallback to local backup on any failure.
|
||||
|
||||
## Available Pattern Types
|
||||
|
||||
When creating guardrails for templates, you can use these prebuilt patterns:
|
||||
|
||||
### Identity Documents
|
||||
- `passport_australia`, `passport_us`, `passport_uk`, `passport_germany`, etc.
|
||||
- `us_ssn`, `us_ssn_no_dash`
|
||||
- `au_tfn`, `au_abn`, `au_medicare`
|
||||
- `nl_bsn_contextual`
|
||||
- `br_cpf`, `br_rg`, `br_cnpj`
|
||||
|
||||
### Financial
|
||||
- `visa`, `mastercard`, `amex`, `discover`, `credit_card`
|
||||
- `iban`
|
||||
|
||||
### Contact Information
|
||||
- `email`
|
||||
- `us_phone`, `br_phone_landline`, `br_phone_mobile`
|
||||
- `street_address`
|
||||
- `br_cep` (Brazilian postal code)
|
||||
|
||||
### Credentials
|
||||
- `aws_access_key`, `aws_secret_key`
|
||||
- `github_token`
|
||||
- `slack_token`
|
||||
- `generic_api_key`
|
||||
|
||||
### Network
|
||||
- `ipv4`, `ipv6`
|
||||
|
||||
### Protected Class
|
||||
- `gender_sexual_orientation`
|
||||
- `race_ethnicity_national_origin`
|
||||
- `religion`
|
||||
- `age_discrimination`
|
||||
- `disability`
|
||||
- `marital_family_status`
|
||||
- `military_status`
|
||||
- `public_assistance`
|
||||
|
||||
See the [full patterns list](https://github.com/BerriAI/litellm/blob/main/litellm/proxy/guardrails/guardrail_hooks/litellm_content_filter/patterns.json) for all available patterns.
|
||||
|
||||
## Related Docs
|
||||
|
||||
- [Guardrail Policies](./guardrail_policies)
|
||||
- [Policy Tags](./policy_tags)
|
||||
- [Content Filter Patterns](../hooks/content_filter)
|
||||
- [Custom Code Guardrails](../hooks/custom_code)
|
||||
|
|
@ -1338,6 +1338,7 @@ litellm_settings:
|
|||
s3_aws_secret_access_key: os.environ/AWS_SECRET_ACCESS_KEY # AWS Secret Access Key for S3
|
||||
s3_path: my-test-path # [OPTIONAL] set path in bucket you want to write logs to
|
||||
s3_endpoint_url: https://s3.amazonaws.com # [OPTIONAL] S3 endpoint URL, if you want to use Backblaze/cloudflare s3 buckets
|
||||
s3_use_virtual_hosted_style: false # [OPTIONAL] use virtual-hosted-style URLs (bucket.endpoint/key) instead of path-style (endpoint/bucket/key). Useful for S3-compatible services like MinIO
|
||||
s3_strip_base64_files: false # [OPTIONAL] remove base64 files before storing in s3
|
||||
```
|
||||
|
||||
|
|
|
|||
|
|
@ -250,11 +250,133 @@ The migrate deploy command:
|
|||
|
||||
### Read-only File System
|
||||
|
||||
If you see a `Permission denied` error, it means the LiteLLM pod is running with a read-only file system.
|
||||
Running LiteLLM with `readOnlyRootFilesystem: true` is a Kubernetes security best practice that prevents container processes from writing to the root filesystem. LiteLLM fully supports this configuration.
|
||||
|
||||
To fix this, just set `LITELLM_MIGRATION_DIR="/path/to/writeable/directory"` in your environment.
|
||||
#### Quick Fix for Permission Errors
|
||||
|
||||
LiteLLM will use this directory to write migration files.
|
||||
If you see a `Permission denied` error, it means the LiteLLM pod is running with a read-only file system. LiteLLM needs writable directories for:
|
||||
- **Database migrations**: Set `LITELLM_MIGRATION_DIR="/path/to/writable/directory"`
|
||||
- **Admin UI**: Set `LITELLM_UI_PATH="/path/to/writable/directory"`
|
||||
- **UI assets/logos**: Set `LITELLM_ASSETS_PATH="/path/to/writable/directory"`
|
||||
|
||||
#### Complete Read-Only Filesystem Setup (Kubernetes)
|
||||
|
||||
For production deployments with enhanced security, use this configuration:
|
||||
|
||||
**Option 1: Using EmptyDir Volumes with InitContainer (Recommended)**
|
||||
|
||||
This approach copies the pre-built UI from the Docker image to writable emptyDir volumes at pod startup.
|
||||
|
||||
```yaml
|
||||
apiVersion: apps/v1
|
||||
kind: Deployment
|
||||
metadata:
|
||||
name: litellm-proxy
|
||||
spec:
|
||||
template:
|
||||
spec:
|
||||
initContainers:
|
||||
- name: setup-ui
|
||||
image: ghcr.io/berriai/litellm:main-stable
|
||||
command:
|
||||
- sh
|
||||
- -c
|
||||
- |
|
||||
cp -r /var/lib/litellm/ui/* /app/var/litellm/ui/ && \
|
||||
cp -r /var/lib/litellm/assets/* /app/var/litellm/assets/
|
||||
volumeMounts:
|
||||
- name: ui-volume
|
||||
mountPath: /app/var/litellm/ui
|
||||
- name: assets-volume
|
||||
mountPath: /app/var/litellm/assets
|
||||
|
||||
containers:
|
||||
- name: litellm
|
||||
image: ghcr.io/berriai/litellm:main-stable
|
||||
env:
|
||||
- name: LITELLM_NON_ROOT
|
||||
value: "true"
|
||||
- name: LITELLM_UI_PATH
|
||||
value: "/app/var/litellm/ui"
|
||||
- name: LITELLM_ASSETS_PATH
|
||||
value: "/app/var/litellm/assets"
|
||||
- name: LITELLM_MIGRATION_DIR
|
||||
value: "/app/migrations"
|
||||
- name: PRISMA_BINARY_CACHE_DIR
|
||||
value: "/app/cache/prisma-python/binaries"
|
||||
- name: XDG_CACHE_HOME
|
||||
value: "/app/cache"
|
||||
securityContext:
|
||||
readOnlyRootFilesystem: true
|
||||
runAsNonRoot: true
|
||||
runAsUser: 101
|
||||
capabilities:
|
||||
drop:
|
||||
- ALL
|
||||
volumeMounts:
|
||||
- name: config
|
||||
mountPath: /app/config.yaml
|
||||
subPath: config.yaml
|
||||
readOnly: true
|
||||
- name: ui-volume
|
||||
mountPath: /app/var/litellm/ui
|
||||
- name: assets-volume
|
||||
mountPath: /app/var/litellm/assets
|
||||
- name: cache
|
||||
mountPath: /app/cache
|
||||
- name: migrations
|
||||
mountPath: /app/migrations
|
||||
|
||||
volumes:
|
||||
- name: config
|
||||
configMap:
|
||||
name: litellm-config
|
||||
- name: ui-volume
|
||||
emptyDir:
|
||||
sizeLimit: 100Mi
|
||||
- name: assets-volume
|
||||
emptyDir:
|
||||
sizeLimit: 10Mi
|
||||
- name: cache
|
||||
emptyDir:
|
||||
sizeLimit: 500Mi
|
||||
- name: migrations
|
||||
emptyDir:
|
||||
sizeLimit: 64Mi
|
||||
```
|
||||
|
||||
**Option 2: Without UI (API-only deployment)**
|
||||
|
||||
If you don't need the admin UI, you can run with minimal configuration:
|
||||
|
||||
```yaml
|
||||
env:
|
||||
- name: LITELLM_NON_ROOT
|
||||
value: "true"
|
||||
- name: LITELLM_MIGRATION_DIR
|
||||
value: "/app/migrations"
|
||||
securityContext:
|
||||
readOnlyRootFilesystem: true
|
||||
```
|
||||
|
||||
The proxy will log a warning about the UI but API endpoints will work normally.
|
||||
|
||||
#### Environment Variables for Read-Only Filesystems
|
||||
|
||||
| Variable | Purpose | Default |
|
||||
|----------|---------|---------|
|
||||
| `LITELLM_UI_PATH` | Admin UI directory | `/var/lib/litellm/ui` (Docker) |
|
||||
| `LITELLM_ASSETS_PATH` | UI assets/logos | `/var/lib/litellm/assets` (Docker) |
|
||||
| `LITELLM_MIGRATION_DIR` | Database migrations | Package directory |
|
||||
| `PRISMA_BINARY_CACHE_DIR` | Prisma binary cache | System default |
|
||||
| `XDG_CACHE_HOME` | General cache directory | System default |
|
||||
|
||||
#### Important Notes
|
||||
|
||||
1. **Migrations**: Always set `LITELLM_MIGRATION_DIR` to a writable emptyDir path
|
||||
2. **Prisma Cache**: Set `PRISMA_BINARY_CACHE_DIR` and `XDG_CACHE_HOME` to writable paths
|
||||
3. **Server Root Path**: If using a custom `server_root_path`, you must pre-process UI files in your Dockerfile as the proxy cannot modify files at runtime with read-only filesystem
|
||||
4. **Automatic Detection**: The UI is automatically detected as pre-restructured if it contains a `.litellm_ui_ready` marker file (created by the official Docker images)
|
||||
|
||||
## 10. Use a Separate Health Check App
|
||||
:::info
|
||||
|
|
|
|||
43
docs/my-website/docs/proxy/pyroscope_profiling.md
Normal file
43
docs/my-website/docs/proxy/pyroscope_profiling.md
Normal file
|
|
@ -0,0 +1,43 @@
|
|||
# Grafana Pyroscope CPU profiling
|
||||
|
||||
LiteLLM proxy can send continuous CPU profiles to [Grafana Pyroscope](https://grafana.com/docs/pyroscope/latest/) when enabled via environment variables. This is optional and off by default.
|
||||
|
||||
## Quick start
|
||||
|
||||
1. **Install the optional dependency** (required only when enabling Pyroscope):
|
||||
|
||||
```bash
|
||||
pip install pyroscope-io
|
||||
```
|
||||
|
||||
Or install the proxy extra:
|
||||
|
||||
```bash
|
||||
pip install "litellm[proxy]"
|
||||
```
|
||||
|
||||
2. **Set environment variables** before starting the proxy:
|
||||
|
||||
| Variable | Required | Description |
|
||||
|----------|----------|-------------|
|
||||
| `LITELLM_ENABLE_PYROSCOPE` | Yes (to enable) | Set to `true` to enable Pyroscope profiling. |
|
||||
| `PYROSCOPE_APP_NAME` | Yes (when enabled) | Application name shown in the Pyroscope UI. |
|
||||
| `PYROSCOPE_SERVER_ADDRESS` | Yes (when enabled) | Pyroscope server URL (e.g. `http://localhost:4040`). |
|
||||
| `PYROSCOPE_SAMPLE_RATE` | No | Sample rate (integer). If unset, the pyroscope-io library default is used. |
|
||||
|
||||
3. **Start the proxy**; profiling will begin automatically when the proxy starts.
|
||||
|
||||
```bash
|
||||
export LITELLM_ENABLE_PYROSCOPE=true
|
||||
export PYROSCOPE_APP_NAME=litellm-proxy
|
||||
export PYROSCOPE_SERVER_ADDRESS=http://localhost:4040
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
||||
4. **View profiles** in the Pyroscope (or Grafana) UI and select your `PYROSCOPE_APP_NAME`.
|
||||
|
||||
## Notes
|
||||
|
||||
- **Optional dependency**: `pyroscope-io` is an optional dependency. If it is not installed and `LITELLM_ENABLE_PYROSCOPE=true`, the proxy will log a warning and continue without profiling.
|
||||
- **Platform support**: The `pyroscope-io` package uses a native extension and is not available on all platforms (e.g. Windows is excluded by the package).
|
||||
- **Other settings**: See [Configuration settings](/proxy/config_settings) for all proxy environment variables.
|
||||
128
docs/my-website/docs/proxy/sync_anthropic_beta_headers.md
Normal file
128
docs/my-website/docs/proxy/sync_anthropic_beta_headers.md
Normal file
|
|
@ -0,0 +1,128 @@
|
|||
# Auto Sync Anthropic Beta Headers
|
||||
|
||||
Automatically keep your Anthropic beta headers configuration up to date without restarting your service. **This allows you to support new Anthropic beta features across all providers without restarting your service.**
|
||||
|
||||
## Overview
|
||||
|
||||
When Anthropic releases new beta features (e.g., new tool capabilities, extended context windows), you typically need to restart your LiteLLM service to get the latest beta header mappings for different providers (Anthropic, Bedrock, Vertex AI, Azure AI).
|
||||
|
||||
With auto-sync, LiteLLM automatically pulls the latest configuration from GitHub's [`anthropic_beta_headers_config.json`](https://github.com/BerriAI/litellm/blob/main/litellm/anthropic_beta_headers_config.json) without requiring a restart. This means:
|
||||
|
||||
- **Zero downtime** when new beta features are released
|
||||
- **Always up-to-date** provider support mappings
|
||||
- **Automatic updates** - set it once and forget it
|
||||
|
||||
## Quick Start
|
||||
|
||||
**Manual sync:**
|
||||
```bash
|
||||
curl -X POST "https://your-proxy-url/reload/anthropic_beta_headers" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN" \
|
||||
-H "Content-Type: application/json"
|
||||
```
|
||||
|
||||
**Automatic sync every 24 hours:**
|
||||
```bash
|
||||
curl -X POST "https://your-proxy-url/schedule/anthropic_beta_headers_reload?hours=24" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN" \
|
||||
-H "Content-Type: application/json"
|
||||
```
|
||||
|
||||
## API Endpoints
|
||||
|
||||
| Endpoint | Method | Description |
|
||||
|----------|--------|-------------|
|
||||
| `/reload/anthropic_beta_headers` | POST | Manual sync |
|
||||
| `/schedule/anthropic_beta_headers_reload?hours={hours}` | POST | Schedule periodic sync |
|
||||
| `/schedule/anthropic_beta_headers_reload` | DELETE | Cancel scheduled sync |
|
||||
| `/schedule/anthropic_beta_headers_reload/status` | GET | Check sync status |
|
||||
|
||||
**Authentication:** Requires admin role or master key
|
||||
|
||||
## Python Example
|
||||
|
||||
```python
|
||||
import requests
|
||||
|
||||
def sync_anthropic_beta_headers(proxy_url, admin_token):
|
||||
response = requests.post(
|
||||
f"{proxy_url}/reload/anthropic_beta_headers",
|
||||
headers={"Authorization": f"Bearer {admin_token}"}
|
||||
)
|
||||
return response.json()
|
||||
|
||||
# Usage
|
||||
result = sync_anthropic_beta_headers("https://your-proxy-url", "your-admin-token")
|
||||
print(result['message'])
|
||||
```
|
||||
|
||||
## Configuration
|
||||
|
||||
**Custom beta headers config URL:**
|
||||
```bash
|
||||
export LITELLM_ANTHROPIC_BETA_HEADERS_URL="https://raw.githubusercontent.com/BerriAI/litellm/main/litellm/anthropic_beta_headers_config.json"
|
||||
```
|
||||
|
||||
**Use local beta headers config:**
|
||||
```bash
|
||||
export LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS=True
|
||||
```
|
||||
|
||||
## Scheduling Automatic Reloads
|
||||
|
||||
Schedule automatic reloads to ensure your proxy always has the latest beta header mappings:
|
||||
|
||||
```bash
|
||||
# Reload every 24 hours
|
||||
curl -X POST "https://your-proxy-url/schedule/anthropic_beta_headers_reload?hours=24" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
**Check reload status:**
|
||||
```bash
|
||||
curl -X GET "https://your-proxy-url/schedule/anthropic_beta_headers_reload/status" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
**Response:**
|
||||
```json
|
||||
{
|
||||
"scheduled": true,
|
||||
"interval_hours": 24,
|
||||
"last_run": "2026-02-13T10:00:00",
|
||||
"next_run": "2026-02-14T10:00:00"
|
||||
}
|
||||
```
|
||||
|
||||
**Cancel scheduled reload:**
|
||||
```bash
|
||||
curl -X DELETE "https://your-proxy-url/schedule/anthropic_beta_headers_reload" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
## Environment Variables
|
||||
|
||||
| Variable | Description | Default |
|
||||
|----------|-------------|---------|
|
||||
| `LITELLM_ANTHROPIC_BETA_HEADERS_URL` | URL to fetch beta headers config from | GitHub main branch |
|
||||
| `LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS` | Set to `True` to use local config only | `False` |
|
||||
|
||||
## How It Works
|
||||
|
||||
1. **Initial Load:** On startup, LiteLLM loads the beta headers configuration from the remote URL (or local file if configured)
|
||||
2. **Caching:** The configuration is cached in memory to avoid repeated fetches on every request
|
||||
3. **Scheduled Reload:** If configured, the proxy checks every 10 seconds whether it's time to reload based on your schedule
|
||||
4. **Manual Reload:** You can trigger an immediate reload via the API endpoint
|
||||
5. **Multi-Pod Support:** In multi-pod deployments, the reload configuration is stored in the database so all pods stay in sync
|
||||
|
||||
## Benefits
|
||||
|
||||
- **No Restarts Required:** Add support for new Anthropic beta features without downtime
|
||||
- **Provider Compatibility:** Automatically get updated mappings for Bedrock, Vertex AI, Azure AI, etc.
|
||||
- **Performance:** Configuration is cached and only reloaded when needed
|
||||
- **Reliability:** Falls back to local configuration if remote fetch fails
|
||||
|
||||
## Related
|
||||
|
||||
- [Model Cost Map Sync](./sync_models_github.md) - Auto-sync model pricing data
|
||||
- [Anthropic Beta Headers](../completion/anthropic.md#beta-features) - Using Anthropic beta features
|
||||
|
|
@ -549,11 +549,14 @@ curl 'http://localhost:4000/key/sk-1234/regenerate' \
|
|||
"models": [
|
||||
"gpt-4",
|
||||
"gpt-3.5-turbo"
|
||||
]
|
||||
],
|
||||
"grace_period": "48h"
|
||||
}'
|
||||
|
||||
```
|
||||
|
||||
**Grace period (optional)**: Set `grace_period` (e.g. `"24h"`, `"2d"`, `"1w"`) to keep the old key valid for a transitional period. Both old and new keys work until the grace period elapses, enabling seamless cutover without production downtime. Omitted or empty = immediate revoke. Can also be set via `LITELLM_KEY_ROTATION_GRACE_PERIOD` env var for scheduled rotations.
|
||||
|
||||
**Read More**
|
||||
|
||||
- [Write rotated keys to secrets manager](https://docs.litellm.ai/docs/secret#aws-secret-manager)
|
||||
|
|
@ -640,11 +643,13 @@ Set these environment variables when starting the proxy:
|
|||
|----------|-------------|---------|
|
||||
| `LITELLM_KEY_ROTATION_ENABLED` | Enable the rotation worker | `false` |
|
||||
| `LITELLM_KEY_ROTATION_CHECK_INTERVAL_SECONDS` | How often to scan for keys to rotate (in seconds) | `86400` (24 hours) |
|
||||
| `LITELLM_KEY_ROTATION_GRACE_PERIOD` | Duration to keep old key valid after rotation (e.g. `24h`, `2d`) | `""` (immediate revoke) |
|
||||
|
||||
**Example:**
|
||||
```bash
|
||||
export LITELLM_KEY_ROTATION_ENABLED=true
|
||||
export LITELLM_KEY_ROTATION_CHECK_INTERVAL_SECONDS=3600 # Check every hour
|
||||
export LITELLM_KEY_ROTATION_GRACE_PERIOD=48h # Keep old key valid for 48h during cutover
|
||||
|
||||
litellm --config config.yaml
|
||||
```
|
||||
|
|
|
|||
|
|
@ -1023,6 +1023,134 @@ curl http://localhost:4000/v1/responses \
|
|||
|
||||
|
||||
|
||||
## Server-side compaction
|
||||
|
||||
For long-running conversations, you can enable **server-side compaction** so that when the rendered context size crosses a threshold, the server automatically runs compaction in-stream and emits a compaction item—no separate `POST /v1/responses/compact` call is required.
|
||||
|
||||
Supported on the OpenAI Responses API when using the `openai` or `azure` provider. Pass `context_management` with a compaction entry and `compact_threshold` (token count; minimum 1000). When the context crosses the threshold, the server compacts in-stream and continues. Chain turns with `previous_response_id` or by appending output items to your next input array. See [OpenAI Compaction guide](https://developers.openai.com/api/docs/guides/compaction) for details.
|
||||
|
||||
For explicit control over when compaction runs, use the standalone compact endpoint (`POST /v1/responses/compact`) instead.
|
||||
|
||||
### Python SDK
|
||||
|
||||
```python showLineNumbers title="Server-side compaction with LiteLLM Python SDK"
|
||||
import litellm
|
||||
|
||||
# Non-streaming: enable compaction when context exceeds 200k tokens
|
||||
response = litellm.responses(
|
||||
model="openai/gpt-4o",
|
||||
input="Your conversation input...",
|
||||
context_management=[{"type": "compaction", "compact_threshold": 200000}],
|
||||
max_output_tokens=1024,
|
||||
)
|
||||
print(response)
|
||||
|
||||
# Streaming: same context_management, compaction runs in-stream if threshold is crossed
|
||||
stream = litellm.responses(
|
||||
model="openai/gpt-4o",
|
||||
input="Your conversation input...",
|
||||
context_management=[{"type": "compaction", "compact_threshold": 200000}],
|
||||
stream=True,
|
||||
)
|
||||
for event in stream:
|
||||
print(event)
|
||||
```
|
||||
|
||||
### LiteLLM Proxy (AI Gateway)
|
||||
|
||||
Use the OpenAI SDK with your proxy as `base_url`, or call the proxy with curl. The proxy forwards `context_management` to the provider.
|
||||
|
||||
**OpenAI Python SDK (proxy as base_url):**
|
||||
|
||||
```python showLineNumbers title="Server-side compaction via LiteLLM Proxy"
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
base_url="http://localhost:4000", # LiteLLM Proxy (AI Gateway)
|
||||
api_key="your-proxy-api-key",
|
||||
)
|
||||
|
||||
response = client.responses.create(
|
||||
model="openai/gpt-4o",
|
||||
input="Your conversation input...",
|
||||
context_management=[{"type": "compaction", "compact_threshold": 200000}],
|
||||
max_output_tokens=1024,
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
**curl (proxy):**
|
||||
|
||||
```bash title="Server-side compaction via curl to LiteLLM Proxy"
|
||||
curl -X POST "http://localhost:4000/v1/responses" \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer your-proxy-api-key" \
|
||||
-d '{
|
||||
"model": "openai/gpt-4o",
|
||||
"input": "Your conversation input...",
|
||||
"context_management": [{"type": "compaction", "compact_threshold": 200000}],
|
||||
"max_output_tokens": 1024
|
||||
}'
|
||||
```
|
||||
|
||||
## Shell tool
|
||||
|
||||
The **Shell tool** lets the model run commands in a hosted container or local runtime (OpenAI Responses API). You pass `tools=[{"type": "shell", "environment": {...}}]`; the `environment` object configures the runtime (e.g. `type: "container_auto"` for auto-provisioned containers). See [OpenAI Shell tool guide](https://developers.openai.com/api/docs/guides/tools-shell) for full options.
|
||||
|
||||
Supported when using the `openai` or `azure` provider with a model that supports the Shell tool.
|
||||
|
||||
### Python SDK
|
||||
|
||||
```python showLineNumbers title="Shell tool with LiteLLM Python SDK"
|
||||
import litellm
|
||||
|
||||
response = litellm.responses(
|
||||
model="openai/gpt-5.2",
|
||||
input="List files in /mnt/data and run python --version.",
|
||||
tools=[{"type": "shell", "environment": {"type": "container_auto"}}],
|
||||
tool_choice="auto",
|
||||
max_output_tokens=1024,
|
||||
)
|
||||
```
|
||||
|
||||
### LiteLLM Proxy (AI Gateway)
|
||||
|
||||
Use the OpenAI SDK with your proxy as `base_url`, or call the proxy with curl. The proxy forwards `tools` (including `type: "shell"`) to the provider.
|
||||
|
||||
**OpenAI Python SDK (proxy as base_url):**
|
||||
|
||||
```python showLineNumbers title="Shell tool via LiteLLM Proxy"
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
base_url="http://localhost:4000",
|
||||
api_key="your-proxy-api-key",
|
||||
)
|
||||
|
||||
response = client.responses.create(
|
||||
model="openai/gpt-5.2",
|
||||
input="List files in /mnt/data.",
|
||||
tools=[{"type": "shell", "environment": {"type": "container_auto"}}],
|
||||
tool_choice="auto",
|
||||
max_output_tokens=1024,
|
||||
)
|
||||
```
|
||||
|
||||
**curl:**
|
||||
|
||||
```bash title="Shell tool via curl to LiteLLM Proxy"
|
||||
curl -X POST "http://localhost:4000/v1/responses" \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer your-proxy-api-key" \
|
||||
-d '{
|
||||
"model": "openai/gpt-5.2",
|
||||
"input": "List files in /mnt/data.",
|
||||
"tools": [{"type": "shell", "environment": {"type": "container_auto"}}],
|
||||
"tool_choice": "auto",
|
||||
"max_output_tokens": 1024
|
||||
}'
|
||||
```
|
||||
|
||||
## Session Management
|
||||
|
||||
LiteLLM Proxy supports session management for all supported models. This allows you to store and fetch conversation history (state) in LiteLLM Proxy.
|
||||
|
|
|
|||
|
|
@ -1,102 +1,48 @@
|
|||
# Troubleshooting & Support
|
||||
|
||||
## Information to Provide When Seeking Help
|
||||
# Issue Reporting
|
||||
|
||||
When reporting issues, please include as much of the following as possible. It's okay if you can't provide everything—especially in production scenarios where the trigger might be unknown. Sharing most of this information will help us assist you more effectively.
|
||||
|
||||
### 1. LiteLLM Configuration File
|
||||
## 1. LiteLLM Configuration File
|
||||
|
||||
Your `config.yaml` file (redact sensitive info like API keys). Include number of workers if not in config.
|
||||
|
||||
### 2. Initialization Command
|
||||
## 2. Initialization Command
|
||||
|
||||
The command used to start LiteLLM (e.g., `litellm --config config.yaml --num_workers 8 --detailed_debug`).
|
||||
|
||||
### 3. LiteLLM Version
|
||||
## 3. LiteLLM Version
|
||||
|
||||
- Current version
|
||||
- Version when the issue first appeared (if different)
|
||||
- Current version
|
||||
- Version when the issue first appeared (if different)
|
||||
- If upgraded, the version changed from → to
|
||||
|
||||
### 4. Environment Variables
|
||||
## 4. Environment Variables
|
||||
|
||||
Non-sensitive environment variables not in your config (e.g., `NUM_WORKERS`, `LITELLM_LOG`, `LITELLM_MODE`). Do not include passwords or API keys.
|
||||
|
||||
### 5. Server Specifications
|
||||
## 5. Server Specifications
|
||||
|
||||
CPU cores, RAM, OS, number of instances/replicas, etc.
|
||||
|
||||
### 6. Database and Redis Usage
|
||||
## 6. Database and Redis Usage
|
||||
|
||||
- **Database:** Using database? (`DATABASE_URL` set), database type and version
|
||||
- **Redis:** Using Redis? Redis version, configuration type (Standalone/Cluster/Sentinel).
|
||||
|
||||
### 7. Endpoints
|
||||
## 7. Endpoints
|
||||
|
||||
The endpoint(s) you're using that are experiencing issues (e.g., `/chat/completions`, `/embeddings`).
|
||||
|
||||
### 8. Request Example
|
||||
## 8. Request Example
|
||||
|
||||
A realistic example of the request causing issues, including expected vs. actual response and any error messages.
|
||||
|
||||
### 9. Error Logs, Stack Traces, and Metrics
|
||||
## 9. Error Logs, Stack Traces, and Metrics
|
||||
|
||||
Full error logs, stack traces, and any images from service metrics (CPU, memory, request rates, etc.) that might help diagnose the issue.
|
||||
|
||||
---
|
||||
|
||||
## UI Issues
|
||||
|
||||
If you're experiencing issues with the LiteLLM Admin UI, please include the following information in addition to the general details above.
|
||||
|
||||
### 1. Steps to Reproduce
|
||||
|
||||
A clear, step-by-step description of how to trigger the issue (e.g., "Navigate to Settings → Team, click 'Create Team', fill in fields, click submit → error appears").
|
||||
|
||||
### 2. LiteLLM Version
|
||||
|
||||
The current version of LiteLLM you're running. Check via `litellm --version` or the UI's settings page.
|
||||
|
||||
### 3. Architecture & Deployment Setup
|
||||
|
||||
Distributed environments are a known source of UI issues. Please describe:
|
||||
|
||||
- **Number of LiteLLM instances/replicas** and how they are deployed (e.g., Kubernetes, Docker Compose, ECS)
|
||||
- **Load balancer** type and configuration (e.g., ALB, Nginx, Cloudflare Tunnel) — include whether sticky sessions are enabled
|
||||
- **How the UI is accessed** — directly via LiteLLM, through a reverse proxy, or behind an ingress controller
|
||||
- **Any CDN or caching layers** between the user and the LiteLLM server
|
||||
|
||||
### 4. Network Tab Requests
|
||||
|
||||
Open your browser's Developer Tools (F12 → Network tab), reproduce the issue, and share:
|
||||
|
||||
- The **failing request(s)** — URL, method, status code, and response body
|
||||
- **Screenshots or HAR export** of the relevant network activity
|
||||
- Any **CORS or mixed-content errors** shown in the Console tab
|
||||
|
||||
### 5. Environment Variables
|
||||
|
||||
Non-sensitive environment variables related to the UI and proxy setup, such as:
|
||||
|
||||
- `LITELLM_MASTER_KEY`
|
||||
- `PROXY_BASE_URL` / `LITELLM_PROXY_BASE_URL`
|
||||
- `UI_BASE_PATH`
|
||||
- Any SSO-related variables (e.g., `GOOGLE_CLIENT_ID`, `MICROSOFT_TENANT`)
|
||||
|
||||
Do **not** include passwords, secrets, or API keys.
|
||||
|
||||
### 6. Browser & Access Details
|
||||
|
||||
- **Browser** and version (e.g., Chrome 120, Firefox 121)
|
||||
- **Access URL** used to reach the UI (redact sensitive parts)
|
||||
- Whether the issue occurs for **all users or specific roles** (Admin, Internal User, etc.)
|
||||
|
||||
### 7. Screenshots or Screen Recordings
|
||||
|
||||
A screenshot or short screen recording of the issue is extremely helpful. Include any visible error messages, toasts, or unexpected behavior.
|
||||
|
||||
---
|
||||
|
||||
## Support Channels
|
||||
|
||||
[Schedule Demo 👋](https://calendly.com/d/4mp-gd3-k5k/berriai-1-1-onboarding-litellm-hosted-version)
|
||||
|
|
@ -109,4 +55,3 @@ Our numbers 📞 +1 (770) 8783-106 / +1 (412) 618-6238
|
|||
Our emails ✉️ ishaan@berri.ai / krrish@berri.ai
|
||||
|
||||
[](https://wa.link/huol9n) [](https://discord.gg/wuPM9dRgDw)
|
||||
|
||||
|
|
|
|||
49
docs/my-website/docs/troubleshoot/ui_issues.md
Normal file
49
docs/my-website/docs/troubleshoot/ui_issues.md
Normal file
|
|
@ -0,0 +1,49 @@
|
|||
# UI Troubleshooting
|
||||
|
||||
If you're experiencing issues with the LiteLLM Admin UI, please include the following information when reporting.
|
||||
|
||||
## 1. Steps to Reproduce
|
||||
|
||||
A clear, step-by-step description of how to trigger the issue (e.g., "Navigate to Settings → Team, click 'Create Team', fill in fields, click submit → error appears").
|
||||
|
||||
## 2. LiteLLM Version
|
||||
|
||||
The current version of LiteLLM you're running. Check via `litellm --version` or the UI's settings page.
|
||||
|
||||
## 3. Architecture & Deployment Setup
|
||||
|
||||
Distributed environments are a known source of UI issues. Please describe:
|
||||
|
||||
- **Number of LiteLLM instances/replicas** and how they are deployed (e.g., Kubernetes, Docker Compose, ECS)
|
||||
- **Load balancer** type and configuration (e.g., ALB, Nginx, Cloudflare Tunnel) — include whether sticky sessions are enabled
|
||||
- **How the UI is accessed** — directly via LiteLLM, through a reverse proxy, or behind an ingress controller
|
||||
- **Any CDN or caching layers** between the user and the LiteLLM server
|
||||
|
||||
## 4. Network Tab Requests
|
||||
|
||||
Open your browser's Developer Tools (F12 → Network tab), reproduce the issue, and share:
|
||||
|
||||
- The **failing request(s)** — URL, method, status code, and response body
|
||||
- **Screenshots or HAR export** of the relevant network activity
|
||||
- Any **CORS or mixed-content errors** shown in the Console tab
|
||||
|
||||
## 5. Environment Variables
|
||||
|
||||
Non-sensitive environment variables related to the UI and proxy setup, such as:
|
||||
|
||||
- `LITELLM_MASTER_KEY`
|
||||
- `PROXY_BASE_URL` / `LITELLM_PROXY_BASE_URL`
|
||||
- `UI_BASE_PATH`
|
||||
- Any SSO-related variables (e.g., `GOOGLE_CLIENT_ID`, `MICROSOFT_TENANT`)
|
||||
|
||||
Do **not** include passwords, secrets, or API keys.
|
||||
|
||||
## 6. Browser & Access Details
|
||||
|
||||
- **Browser** and version (e.g., Chrome 120, Firefox 121)
|
||||
- **Access URL** used to reach the UI (redact sensitive parts)
|
||||
- Whether the issue occurs for **all users or specific roles** (Admin, Internal User, etc.)
|
||||
|
||||
## 7. Screenshots or Screen Recordings
|
||||
|
||||
A screenshot or short screen recording of the issue is extremely helpful. Include any visible error messages, toasts, or unexpected behavior.
|
||||
|
|
@ -1,8 +1,8 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Claude Code - Fixing Invalid Beta Header Errors
|
||||
# Claude Code - Managing Anthropic Beta Headers
|
||||
|
||||
When using Claude Code with LiteLLM and non-Anthropic providers (Bedrock, Azure AI, Vertex AI), you may encounter "invalid beta header" errors. This guide explains how to fix these errors locally or contribute a fix to LiteLLM.
|
||||
When using Claude Code with LiteLLM and non-Anthropic providers (Bedrock, Azure AI, Vertex AI), you need to ensure that only supported beta headers are sent to each provider. This guide explains how to add support for new beta headers or fix invalid beta header errors.
|
||||
|
||||
## What Are Beta Headers?
|
||||
|
||||
|
|
@ -12,7 +12,7 @@ Anthropic uses beta headers to enable experimental features in Claude. When you
|
|||
anthropic-beta: prompt-caching-scope-2026-01-05,advanced-tool-use-2025-11-20
|
||||
```
|
||||
|
||||
However, not all providers support all Anthropic beta features. When an unsupported beta header is sent to a provider, you'll see an error.
|
||||
However, not all providers support all Anthropic beta features. LiteLLM uses `anthropic_beta_headers_config.json` to manage which beta headers are supported by each provider.
|
||||
|
||||
## Common Error Message
|
||||
|
||||
|
|
@ -22,17 +22,22 @@ Error: The model returned the following errors: invalid beta flag
|
|||
|
||||
## How LiteLLM Handles Beta Headers
|
||||
|
||||
LiteLLM automatically filters out unsupported beta headers using a configuration file:
|
||||
LiteLLM uses a strict validation approach with a configuration file:
|
||||
|
||||
```
|
||||
litellm/litellm/anthropic_beta_headers_config.json
|
||||
```
|
||||
|
||||
This JSON file lists which beta headers are **unsupported** for each provider. Headers not in the unsupported list are passed through to the provider.
|
||||
This JSON file contains a **mapping** of beta headers for each provider:
|
||||
- **Keys**: Input beta header names (from Anthropic)
|
||||
- **Values**: Provider-specific header names (or `null` if unsupported)
|
||||
- **Validation**: Only headers present in the mapping with non-null values are forwarded
|
||||
|
||||
## Quick Fix: Update Config Locally
|
||||
This enforces stricter validation than just filtering unsupported headers - headers must be explicitly defined to be allowed.
|
||||
|
||||
If you encounter an invalid beta header error, you can fix it immediately by updating the config file locally.
|
||||
## Adding Support for a New Beta Header
|
||||
|
||||
When Anthropic releases a new beta feature, you need to add it to the configuration file for each provider.
|
||||
|
||||
### Step 1: Locate the Config File
|
||||
|
||||
|
|
@ -46,46 +51,75 @@ cd $(python -c "import litellm; import os; print(os.path.dirname(litellm.__file_
|
|||
# litellm/anthropic_beta_headers_config.json
|
||||
```
|
||||
|
||||
### Step 2: Add the Unsupported Header
|
||||
### Step 2: Add the New Beta Header
|
||||
|
||||
Open `anthropic_beta_headers_config.json` and add the problematic header to the appropriate provider's list:
|
||||
Open `anthropic_beta_headers_config.json` and add the new header to each provider's mapping:
|
||||
|
||||
```json title="anthropic_beta_headers_config.json"
|
||||
{
|
||||
"description": "Unsupported Anthropic beta headers for each provider. Headers listed here will be dropped. Headers not listed are passed through as-is.",
|
||||
"anthropic": [],
|
||||
"azure_ai": [],
|
||||
"bedrock_converse": [
|
||||
"prompt-caching-scope-2026-01-05",
|
||||
"bash_20250124",
|
||||
"bash_20241022",
|
||||
"text_editor_20250124",
|
||||
"text_editor_20241022",
|
||||
"compact-2026-01-12",
|
||||
"advanced-tool-use-2025-11-20",
|
||||
"web-fetch-2025-09-10",
|
||||
"code-execution-2025-08-25",
|
||||
"skills-2025-10-02",
|
||||
"files-api-2025-04-14"
|
||||
],
|
||||
"bedrock": [
|
||||
"advanced-tool-use-2025-11-20",
|
||||
"prompt-caching-scope-2026-01-05",
|
||||
"structured-outputs-2025-11-13",
|
||||
"web-fetch-2025-09-10",
|
||||
"code-execution-2025-08-25",
|
||||
"skills-2025-10-02",
|
||||
"files-api-2025-04-14"
|
||||
],
|
||||
"vertex_ai": [
|
||||
"prompt-caching-scope-2026-01-05"
|
||||
]
|
||||
"description": "Mapping of Anthropic beta headers for each provider. Keys are input header names, values are provider-specific header names (or null if unsupported). Only headers present in mapping keys with non-null values can be forwarded.",
|
||||
"anthropic": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"new-feature-2026-03-01": "new-feature-2026-03-01",
|
||||
...
|
||||
},
|
||||
"azure_ai": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"new-feature-2026-03-01": "new-feature-2026-03-01",
|
||||
...
|
||||
},
|
||||
"bedrock_converse": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"new-feature-2026-03-01": null,
|
||||
...
|
||||
},
|
||||
"bedrock": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"new-feature-2026-03-01": null,
|
||||
...
|
||||
},
|
||||
"vertex_ai": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"new-feature-2026-03-01": null,
|
||||
...
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Step 3: Restart Your Application
|
||||
**Key Points:**
|
||||
- **Supported headers**: Set the value to the provider-specific header name (often the same as the key)
|
||||
- **Unsupported headers**: Set the value to `null`
|
||||
- **Header transformations**: Some providers use different header names (e.g., Bedrock maps `advanced-tool-use-2025-11-20` to `tool-search-tool-2025-10-19`)
|
||||
- **Alphabetical order**: Keep headers sorted alphabetically for maintainability
|
||||
|
||||
After updating the config file, restart your LiteLLM proxy or application:
|
||||
### Step 3: Reload Configuration (No Restart Required!)
|
||||
|
||||
**Option 1: Dynamic Reload Without Restart**
|
||||
|
||||
Instead of restarting your application, you can dynamically reload the beta headers configuration using environment variables and API endpoints:
|
||||
|
||||
```bash
|
||||
# Set environment variable to fetch from remote URL (Do this if you want to point it to some other URL)
|
||||
export LITELLM_ANTHROPIC_BETA_HEADERS_URL="https://raw.githubusercontent.com/BerriAI/litellm/main/litellm/anthropic_beta_headers_config.json"
|
||||
|
||||
# Manually trigger reload via API (no restart needed!)
|
||||
curl -X POST "https://your-proxy-url/reload/anthropic_beta_headers" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
**Option 2: Schedule Automatic Reloads**
|
||||
|
||||
Set up automatic reloading to always stay up-to-date with the latest beta headers:
|
||||
|
||||
```bash
|
||||
# Reload configuration every 24 hours
|
||||
curl -X POST "https://your-proxy-url/schedule/anthropic_beta_headers_reload?hours=24" \
|
||||
-H "Authorization: Bearer YOUR_ADMIN_TOKEN"
|
||||
```
|
||||
|
||||
**Option 3: Traditional Restart**
|
||||
|
||||
If you prefer the traditional approach, restart your LiteLLM proxy or application:
|
||||
|
||||
```bash
|
||||
# If using LiteLLM proxy
|
||||
|
|
@ -95,11 +129,70 @@ litellm --config config.yaml
|
|||
# Just restart your Python application
|
||||
```
|
||||
|
||||
The updated configuration will be loaded automatically.
|
||||
:::tip Zero-Downtime Updates
|
||||
With dynamic reloading, you can fix invalid beta header errors **without restarting your service**! This is especially useful in production environments where downtime is costly.
|
||||
|
||||
See [Auto Sync Anthropic Beta Headers](../proxy/sync_anthropic_beta_headers.md) for complete documentation.
|
||||
:::
|
||||
|
||||
## Fixing Invalid Beta Header Errors
|
||||
|
||||
If you encounter an "invalid beta flag" error, it means a beta header is being sent that the provider doesn't support.
|
||||
|
||||
### Step 1: Identify the Problematic Header
|
||||
|
||||
Check your logs to see which header is causing the issue:
|
||||
|
||||
```bash
|
||||
Error: The model returned the following errors: invalid beta flag: new-feature-2026-03-01
|
||||
```
|
||||
|
||||
### Step 2: Update the Config
|
||||
|
||||
Set the header value to `null` for that provider:
|
||||
|
||||
```json title="anthropic_beta_headers_config.json"
|
||||
{
|
||||
"bedrock_converse": {
|
||||
"new-feature-2026-03-01": null
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Step 3: Restart and Test
|
||||
|
||||
Restart your application and verify the header is now filtered out.
|
||||
|
||||
## Contributing a Fix to LiteLLM
|
||||
|
||||
Help the community by contributing your fix! If your local changes work, please raise a PR with the addition of the header and we will merge it.
|
||||
Help the community by contributing your fix!
|
||||
|
||||
### What to Include in Your PR
|
||||
|
||||
1. **Update the config file**: Add the new beta header to `litellm/anthropic_beta_headers_config.json`
|
||||
2. **Test your changes**: Verify the header is correctly filtered/mapped for each provider
|
||||
3. **Documentation**: Include provider documentation links showing which headers are supported
|
||||
|
||||
### Example PR Description
|
||||
|
||||
```markdown
|
||||
## Add support for new-feature-2026-03-01 beta header
|
||||
|
||||
### Changes
|
||||
- Added `new-feature-2026-03-01` to anthropic_beta_headers_config.json
|
||||
- Set to `null` for bedrock_converse (unsupported)
|
||||
- Set to header name for anthropic, azure_ai (supported)
|
||||
|
||||
### Testing
|
||||
Tested with:
|
||||
- ✅ Anthropic: Header passed through correctly
|
||||
- ✅ Azure AI: Header passed through correctly
|
||||
- ✅ Bedrock Converse: Header filtered out (returns error without fix)
|
||||
|
||||
### References
|
||||
- Anthropic docs: [link]
|
||||
- AWS Bedrock docs: [link]
|
||||
```
|
||||
|
||||
|
||||
## How Beta Header Filtering Works
|
||||
|
|
@ -116,14 +209,71 @@ sequenceDiagram
|
|||
CC->>LP: Request with beta headers
|
||||
Note over CC,LP: anthropic-beta: header1,header2,header3
|
||||
|
||||
LP->>Config: Load unsupported headers for provider
|
||||
Config-->>LP: Returns unsupported list
|
||||
LP->>Config: Load header mapping for provider
|
||||
Config-->>LP: Returns mapping (header→value or null)
|
||||
|
||||
Note over LP: Filter headers:<br/>- Remove unsupported<br/>- Keep supported
|
||||
Note over LP: Validate & Transform:<br/>1. Check if header exists in mapping<br/>2. Filter out null values<br/>3. Map to provider-specific names
|
||||
|
||||
LP->>Provider: Request with filtered headers
|
||||
Note over LP,Provider: anthropic-beta: header2<br/>(header1, header3 removed)
|
||||
LP->>Provider: Request with filtered & mapped headers
|
||||
Note over LP,Provider: anthropic-beta: mapped-header2<br/>(header1, header3 filtered out)
|
||||
|
||||
Provider-->>LP: Success response
|
||||
LP-->>CC: Response
|
||||
```
|
||||
```
|
||||
|
||||
### Filtering Rules
|
||||
|
||||
1. **Header must exist in mapping**: Unknown headers are filtered out
|
||||
2. **Header must have non-null value**: Headers with `null` values are filtered out
|
||||
3. **Header transformation**: Headers are mapped to provider-specific names (e.g., `advanced-tool-use-2025-11-20` → `tool-search-tool-2025-10-19` for Bedrock)
|
||||
|
||||
### Example
|
||||
|
||||
Request with headers:
|
||||
```
|
||||
anthropic-beta: advanced-tool-use-2025-11-20,computer-use-2025-01-24,unknown-header
|
||||
```
|
||||
|
||||
For Bedrock Converse:
|
||||
- ✅ `computer-use-2025-01-24` → `computer-use-2025-01-24` (supported, passed through)
|
||||
- ❌ `advanced-tool-use-2025-11-20` → filtered out (null value in config)
|
||||
- ❌ `unknown-header` → filtered out (not in config)
|
||||
|
||||
Result sent to Bedrock:
|
||||
```
|
||||
anthropic-beta: computer-use-2025-01-24
|
||||
```
|
||||
|
||||
## Dynamic Configuration Management (No Restart Required!)
|
||||
|
||||
### Environment Variables
|
||||
|
||||
Control how LiteLLM loads the beta headers configuration:
|
||||
|
||||
| Variable | Description | Default |
|
||||
|----------|-------------|---------|
|
||||
| `LITELLM_ANTHROPIC_BETA_HEADERS_URL` | URL to fetch config from | GitHub main branch |
|
||||
| `LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS` | Set to `True` to use local config only | `False` |
|
||||
|
||||
**Example: Use Custom Config URL**
|
||||
```bash
|
||||
export LITELLM_ANTHROPIC_BETA_HEADERS_URL="https://your-company.com/custom-beta-headers.json"
|
||||
```
|
||||
|
||||
**Example: Use Local Config Only (No Remote Fetching)**
|
||||
```bash
|
||||
export LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS=True
|
||||
```
|
||||
## Provider-Specific Notes
|
||||
|
||||
### Bedrock
|
||||
- Beta headers appear in both HTTP headers AND request body (`additionalModelRequestFields.anthropic_beta`)
|
||||
- Some headers are transformed (e.g., `advanced-tool-use` → `tool-search-tool`)
|
||||
|
||||
### Azure AI
|
||||
- Uses same header names as Anthropic
|
||||
- Some features not yet supported (check config for null values)
|
||||
|
||||
### Vertex AI
|
||||
- Some headers are transformed to match Vertex AI's implementation
|
||||
- Limited beta feature support compared to Anthropic
|
||||
|
|
@ -9,7 +9,7 @@ Note: LiteLLM supports OAuth for MCP servers as well. [Learn more](https://docs.
|
|||
|
||||
## Connecting MCP Servers
|
||||
|
||||
You can also connect MCP servers to Claude Code via LiteLLM Proxy.
|
||||
You can connect MCP servers to Claude Code via LiteLLM Proxy.
|
||||
|
||||
|
||||
1. Add the MCP server to your `config.yaml`
|
||||
|
|
@ -23,6 +23,7 @@ In this example, we'll add the Github MCP server to our `config.yaml`
|
|||
mcp_servers:
|
||||
github_mcp:
|
||||
url: "https://api.githubcopilot.com/mcp"
|
||||
transport: "http"
|
||||
auth_type: oauth2
|
||||
client_id: os.environ/GITHUB_OAUTH_CLIENT_ID
|
||||
client_secret: os.environ/GITHUB_OAUTH_CLIENT_SECRET
|
||||
|
|
@ -34,31 +35,70 @@ mcp_servers:
|
|||
In this example, we'll add the Atlassian MCP server to our `config.yaml`
|
||||
|
||||
```yaml title="config.yaml" showLineNumbers
|
||||
atlassian_mcp:
|
||||
server_id: atlassian_mcp_id
|
||||
url: "https://mcp.atlassian.com/v1/sse"
|
||||
transport: "sse"
|
||||
auth_type: oauth2
|
||||
mcp_servers:
|
||||
atlassian_mcp:
|
||||
url: "https://mcp.atlassian.com/v1/mcp"
|
||||
transport: "http"
|
||||
auth_type: oauth2
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
:::important
|
||||
The server name under `mcp_servers:` (e.g. `atlassian_mcp`, `github_mcp`) **must match** the name used in the Claude Code URL path (`/mcp/<server_name>`). A mismatch will cause a 404 error during OAuth.
|
||||
:::
|
||||
|
||||
2. Start LiteLLM Proxy
|
||||
|
||||
Since Claude Code needs a publicly accessible URL for the OAuth callback, expose your proxy via ngrok or a similar tool.
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
3. Use the MCP server in Claude Code
|
||||
|
||||
```bash
|
||||
claude mcp add --transport http litellm_proxy http://0.0.0.0:4000/github_mcp/mcp --header "Authorization: Bearer sk-LITELLM_VIRTUAL_KEY"
|
||||
# In a separate terminal — expose proxy for OAuth callbacks
|
||||
ngrok http 4000
|
||||
```
|
||||
|
||||
For MCP servers that require dynamic client registration (such as Atlassian), please set `x-litellm-api-key: Bearer sk-LITELLM_VIRTUAL_KEY` instead of using `Authorization: Bearer LITELLM_VIRTUAL_KEY`.
|
||||
3. Add the MCP server to Claude Code
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="github" label="GitHub MCP">
|
||||
|
||||
```bash
|
||||
claude mcp add --transport http litellm-github https://your-ngrok-url.ngrok-free.dev/mcp/github_mcp \
|
||||
--header "x-litellm-api-key: Bearer sk-1234"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="atlassian" label="Atlassian MCP">
|
||||
|
||||
```bash
|
||||
claude mcp add --transport http litellm-atlassian https://your-ngrok-url.ngrok-free.dev/mcp/atlassian_mcp \
|
||||
--header "x-litellm-api-key: Bearer sk-1234"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
**Parameter breakdown:**
|
||||
|
||||
| Parameter | Description |
|
||||
|-----------|-------------|
|
||||
| `--transport http` | Use HTTP transport for the MCP connection |
|
||||
| `litellm-atlassian` | The name for this MCP server **on Claude Code** — can be anything you choose |
|
||||
| `https://your-ngrok-url.ngrok-free.dev/mcp/atlassian_mcp` | The LiteLLM proxy URL. Format: `<PROXY_URL>/mcp/<server_name_on_litellm>`. The `atlassian_mcp` part **must match** the key under `mcp_servers:` in your LiteLLM proxy config |
|
||||
| `--header "x-litellm-api-key: Bearer sk-1234"` | Your LiteLLM virtual key for authentication to the proxy |
|
||||
|
||||
You can also add the MCP server directly to your `~/.claude.json` file instead of using `claude mcp add`. [See Claude Code docs](https://docs.anthropic.com/en/docs/claude-code/mcp).
|
||||
|
||||
:::note
|
||||
For MCP servers that require OAuth (such as Atlassian), use `x-litellm-api-key` instead of `Authorization` for the LiteLLM virtual key. The `Authorization` header is reserved for the OAuth flow.
|
||||
:::
|
||||
|
||||
4. Authenticate via Claude Code
|
||||
|
||||
|
|
@ -68,24 +108,20 @@ a. Start Claude Code
|
|||
claude
|
||||
```
|
||||
|
||||
b. Authenticate via Claude Code
|
||||
b. Open the MCP menu
|
||||
|
||||
```bash
|
||||
/mcp
|
||||
```
|
||||
|
||||
c. Select the MCP server
|
||||
c. Select the MCP server (e.g. `litellm-atlassian`)
|
||||
|
||||
```bash
|
||||
> litellm_proxy
|
||||
```
|
||||
|
||||
d. Start Oauth flow via Claude Code
|
||||
d. Start the OAuth flow
|
||||
|
||||
```bash
|
||||
> 1. Authenticate
|
||||
2. Reconnect
|
||||
3. Disable
|
||||
3. Disable
|
||||
```
|
||||
|
||||
e. Once completed, you should see this success message:
|
||||
|
|
|
|||
BIN
docs/my-website/img/policy_team_attach.png
Normal file
BIN
docs/my-website/img/policy_team_attach.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 225 KiB |
BIN
docs/my-website/img/policy_test_matching.png
Normal file
BIN
docs/my-website/img/policy_test_matching.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 200 KiB |
BIN
docs/my-website/img/release_notes/guard_actions.png
Normal file
BIN
docs/my-website/img/release_notes/guard_actions.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 506 KiB |
BIN
docs/my-website/img/ui_access_groups.png
Normal file
BIN
docs/my-website/img/ui_access_groups.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 338 KiB |
7
docs/my-website/package-lock.json
generated
7
docs/my-website/package-lock.json
generated
|
|
@ -20455,6 +20455,13 @@
|
|||
"url": "https://opencollective.com/webpack"
|
||||
}
|
||||
},
|
||||
"node_modules/search-insights": {
|
||||
"version": "2.17.3",
|
||||
"resolved": "https://registry.npmjs.org/search-insights/-/search-insights-2.17.3.tgz",
|
||||
"integrity": "sha512-RQPdCYTa8A68uM2jwxoY842xDhvx3E5LFL1LxvxCNMev4o5mLuokczhzjAgGwUZBAmOKZknArSxLKmXtIi2AxQ==",
|
||||
"license": "MIT",
|
||||
"peer": true
|
||||
},
|
||||
"node_modules/section-matter": {
|
||||
"version": "1.0.0",
|
||||
"resolved": "https://registry.npmjs.org/section-matter/-/section-matter-1.0.0.tgz",
|
||||
|
|
|
|||
433
docs/my-website/release_notes/v1.81.12.md
Normal file
433
docs/my-website/release_notes/v1.81.12.md
Normal file
|
|
@ -0,0 +1,433 @@
|
|||
---
|
||||
title: "[Preview] v1.81.12 - Guardrail Policy Templates & Action Builder"
|
||||
slug: "v1-81-12"
|
||||
date: 2026-02-14T00:00:00
|
||||
authors:
|
||||
- name: Krrish Dholakia
|
||||
title: CEO, LiteLLM
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: CTO, LiteLLM
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
## Deploy this version
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import Image from '@theme/IdealImage';
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="docker" label="Docker">
|
||||
|
||||
``` showLineNumbers title="docker run litellm"
|
||||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
ghcr.io/berriai/litellm:main-v1.81.12.rc.1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="pip" label="Pip">
|
||||
|
||||
``` showLineNumbers title="pip install litellm"
|
||||
pip install litellm==1.81.12.rc1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Key Highlights
|
||||
|
||||
- **Policy Templates** - [Pre-configured guardrail policy templates for common safety and compliance use-cases (including NSFW, toxic content, and child safety)](../../docs/proxy/guardrails/policy_templates)
|
||||
- **Guardrail Action Builder** - [Build and customize guardrail policy flows with the new action-builder UI and conditional execution support](../../docs/proxy/guardrails/policy_templates)
|
||||
- **MCP OAuth2 M2M + Tracing** - [Add machine-to-machine OAuth2 support for MCP servers and OpenTelemetry tracing for MCP calls through AI Gateway](../../docs/mcp)
|
||||
- **Responses API `shell` Tool & `context_management` support** - [Server-side context management (compaction) and Shell tool support for the OpenAI Responses API](../../docs/response_api)
|
||||
- **Access Groups** - [Create access groups to manage model, MCP server, and agent access across teams and keys](../../docs/proxy/access_groups)
|
||||
- **50+ New Bedrock Regional Model Entries** - DeepSeek V3.2, MiniMax M2.1, Kimi K2.5, Qwen3 Coder Next, and NVIDIA Nemotron Nano across multiple regions
|
||||
- **Add Semgrep & fix OOMs** - [Static analysis rules and out-of-memory fixes](#add-semgrep--fix-ooms) - [PR #20912](https://github.com/BerriAI/litellm/pull/20912)
|
||||
|
||||
---
|
||||
|
||||
## Add Semgrep & fix OOMs
|
||||
|
||||
This release fixes out-of-memory (OOM) risks from unbounded `asyncio.Queue()` usage. Log queues (e.g. GCS bucket) and DB spend-update queues were previously unbounded and could grow without limit under load. They now use a configurable max size (`LITELLM_ASYNCIO_QUEUE_MAXSIZE`, default 1000); when full, queues flush immediately to make room instead of growing memory. A Semgrep rule (`.semgrep/rules/python/unbounded-memory.yml`) was added to flag similar unbounded-memory patterns in future code. [PR #20912](https://github.com/BerriAI/litellm/pull/20912)
|
||||
|
||||
---
|
||||
|
||||
## Guardrail Action Builder
|
||||
|
||||
This release adds a visual action builder for guardrail policies with conditional execution support. You can now chain guardrails into multi-step pipelines — if a simple guardrail fails, route to an advanced one instead of immediately blocking. Each step has configurable ON PASS and ON FAIL actions (Next Step, Block, or Allow), and you can test the full pipeline with a sample message before saving.
|
||||
|
||||

|
||||
|
||||
### Access Groups
|
||||
|
||||
Access Groups simplify defining resource access across your organization. One group can grant access to models, MCP servers, and agents—simply attach it to a key or team. Create groups in the Admin UI, define which resources each group includes, then assign the group when creating keys or teams. Updates to a group apply automatically to all attached keys and teams.
|
||||
|
||||
<Image img={require('../img/ui_access_groups.png')} />
|
||||
|
||||
## New Providers and Endpoints
|
||||
|
||||
### New Providers (2 new providers)
|
||||
|
||||
| Provider | Supported LiteLLM Endpoints | Description |
|
||||
| -------- | --------------------------- | ----------- |
|
||||
| [Scaleway](../../docs/providers/scaleway) | `/chat/completions` | Scaleway Generative APIs for chat completions |
|
||||
| [Sarvam AI](../../docs/providers/sarvam) | `/chat/completions`, `/audio/transcriptions`, `/audio/speech` | Sarvam AI STT and TTS support for Indian languages |
|
||||
|
||||
---
|
||||
|
||||
## New Models / Updated Models
|
||||
|
||||
#### New Model Support (19 highlighted models)
|
||||
|
||||
| Provider | Model | Context Window | Input ($/1M tokens) | Output ($/1M tokens) |
|
||||
| -------- | ----- | -------------- | ------------------- | -------------------- |
|
||||
| AWS Bedrock | `deepseek.v3.2` | 164K | $0.62 | $1.85 |
|
||||
| AWS Bedrock | `minimax.minimax-m2.1` | 196K | $0.30 | $1.20 |
|
||||
| AWS Bedrock | `moonshotai.kimi-k2.5` | 262K | $0.60 | $3.00 |
|
||||
| AWS Bedrock | `moonshotai.kimi-k2-thinking` | 262K | $0.73 | $3.03 |
|
||||
| AWS Bedrock | `qwen.qwen3-coder-next` | 262K | $0.50 | $1.20 |
|
||||
| AWS Bedrock | `nvidia.nemotron-nano-3-30b` | 262K | $0.06 | $0.24 |
|
||||
| Azure AI | `azure_ai/kimi-k2.5` | 262K | $0.60 | $3.00 |
|
||||
| Vertex AI | `vertex_ai/zai-org/glm-5-maas` | 200K | $1.00 | $3.20 |
|
||||
| MiniMax | `minimax/MiniMax-M2.5` | 1M | $0.30 | $1.20 |
|
||||
| MiniMax | `minimax/MiniMax-M2.5-lightning` | 1M | $0.30 | $2.40 |
|
||||
| Dashscope | `dashscope/qwen3-max` | 258K | Tiered pricing | Tiered pricing |
|
||||
| Perplexity | `perplexity/preset/pro-search` | - | Per-request | Per-request |
|
||||
| Perplexity | `perplexity/openai/gpt-4o` | - | Per-request | Per-request |
|
||||
| Perplexity | `perplexity/openai/gpt-5.2` | - | Per-request | Per-request |
|
||||
| Vercel AI Gateway | `vercel_ai_gateway/anthropic/claude-opus-4.6` | 200K | $5.00 | $25.00 |
|
||||
| Vercel AI Gateway | `vercel_ai_gateway/anthropic/claude-sonnet-4` | 200K | $3.00 | $15.00 |
|
||||
| Vercel AI Gateway | `vercel_ai_gateway/anthropic/claude-haiku-4.5` | 200K | $1.00 | $5.00 |
|
||||
| Sarvam AI | `sarvam/sarvam-m` | 8K | Free tier | Free tier |
|
||||
| Anthropic | `fast/claude-opus-4-6` | 1M | $30.00 | $150.00 |
|
||||
|
||||
*Note: AWS Bedrock models are available across multiple regions (us-east-1, us-east-2, us-west-2, eu-central-1, eu-north-1, ap-northeast-1, ap-south-1, ap-southeast-3, sa-east-1). 54 regional model entries were added in total.*
|
||||
|
||||
#### Features
|
||||
|
||||
- **[Anthropic](../../docs/providers/anthropic)**
|
||||
- Enable non-tool structured outputs on Claude Opus 4.5 and 4.6 using `output_format` param - [PR #20548](https://github.com/BerriAI/litellm/pull/20548)
|
||||
- Add support for `anthropic_messages` call type in prompt caching - [PR #19233](https://github.com/BerriAI/litellm/pull/19233)
|
||||
- Managing Anthropic Beta Headers with remote URL fetching - [PR #20935](https://github.com/BerriAI/litellm/pull/20935), [PR #21110](https://github.com/BerriAI/litellm/pull/21110)
|
||||
- Remove `x-anthropic-billing` block - [PR #20951](https://github.com/BerriAI/litellm/pull/20951)
|
||||
- Use Authorization Bearer for OAuth tokens instead of x-api-key - [PR #21039](https://github.com/BerriAI/litellm/pull/21039)
|
||||
- Filter unsupported JSON schema constraints for structured outputs - [PR #20813](https://github.com/BerriAI/litellm/pull/20813)
|
||||
- New Claude Opus 4.6 features for `/v1/messages` - [PR #20733](https://github.com/BerriAI/litellm/pull/20733)
|
||||
- Fix `reasoning_effort=None` and `"none"` should return None for Opus 4.6 - [PR #20800](https://github.com/BerriAI/litellm/pull/20800)
|
||||
|
||||
- **[AWS Bedrock](../../docs/providers/bedrock)**
|
||||
- Extend model support with 4 new beta models - [PR #21035](https://github.com/BerriAI/litellm/pull/21035)
|
||||
- Add Claude Opus 4.6 to `_supports_tool_search_on_bedrock` - [PR #21017](https://github.com/BerriAI/litellm/pull/21017)
|
||||
- Correct Bedrock Claude Opus 4.6 model IDs (remove `:0` suffix) - [PR #20564](https://github.com/BerriAI/litellm/pull/20564), [PR #20671](https://github.com/BerriAI/litellm/pull/20671)
|
||||
- Add `output_config` as supported param - [PR #20748](https://github.com/BerriAI/litellm/pull/20748)
|
||||
|
||||
- **[Vertex AI](../../docs/providers/vertex)**
|
||||
- Add Vertex GLM-5 model support - [PR #21053](https://github.com/BerriAI/litellm/pull/21053)
|
||||
- Propagate `extra_headers` anthropic-beta to request body - [PR #20666](https://github.com/BerriAI/litellm/pull/20666)
|
||||
- Preserve `usageMetadata` in `_hidden_params` - [PR #20559](https://github.com/BerriAI/litellm/pull/20559)
|
||||
- Map `IMAGE_PROHIBITED_CONTENT` to `content_filter` - [PR #20524](https://github.com/BerriAI/litellm/pull/20524)
|
||||
- Add RAG ingest for Vertex AI - [PR #21120](https://github.com/BerriAI/litellm/pull/21120)
|
||||
|
||||
- **[OCI / Cohere](../../docs/providers/cohere)**
|
||||
- OCI Cohere responseFormat/Pydantic support - [PR #20663](https://github.com/BerriAI/litellm/pull/20663)
|
||||
- Fix OCI Cohere system messages by populating `preambleOverride` - [PR #20958](https://github.com/BerriAI/litellm/pull/20958)
|
||||
|
||||
- **[Perplexity](../../docs/providers/perplexity)**
|
||||
- Perplexity Research API support with preset search - [PR #20860](https://github.com/BerriAI/litellm/pull/20860)
|
||||
|
||||
- **[MiniMax](../../docs/providers/minimax)**
|
||||
- Add MiniMax-M2.5 and MiniMax-M2.5-lightning models - [PR #21054](https://github.com/BerriAI/litellm/pull/21054)
|
||||
|
||||
- **[Kimi / Moonshot](../../docs/providers/moonshot)**
|
||||
- Add Kimi model pricing by region - [PR #20855](https://github.com/BerriAI/litellm/pull/20855)
|
||||
- Add `moonshotai.kimi-k2.5` - [PR #20863](https://github.com/BerriAI/litellm/pull/20863)
|
||||
|
||||
- **[Dashscope](../../docs/providers/dashscope)**
|
||||
- Add `dashscope/qwen3-max` model with tiered pricing - [PR #20919](https://github.com/BerriAI/litellm/pull/20919)
|
||||
|
||||
- **[Vercel AI Gateway](../../docs/providers/vercel_ai_gateway)**
|
||||
- Add new Vercel AI Anthropic models - [PR #20745](https://github.com/BerriAI/litellm/pull/20745)
|
||||
|
||||
- **[Azure AI](../../docs/providers/azure_ai)**
|
||||
- Add `azure_ai/kimi-k2.5` to Azure model DB - [PR #20896](https://github.com/BerriAI/litellm/pull/20896)
|
||||
- Support Azure AD token auth for non-Claude azure_ai models - [PR #20981](https://github.com/BerriAI/litellm/pull/20981)
|
||||
- Fix Azure batches issues - [PR #21092](https://github.com/BerriAI/litellm/pull/21092)
|
||||
|
||||
- **[DeepSeek](../../docs/providers/deepseek)**
|
||||
- Sync DeepSeek model metadata and add bare-name fallback - [PR #20938](https://github.com/BerriAI/litellm/pull/20938)
|
||||
|
||||
- **[Gemini](../../docs/providers/gemini)**
|
||||
- Handle image in assistant message for Gemini - [PR #20845](https://github.com/BerriAI/litellm/pull/20845)
|
||||
- Add missing tpm/rpm for Gemini models - [PR #21175](https://github.com/BerriAI/litellm/pull/21175)
|
||||
|
||||
- **General**
|
||||
- Add 30 missing models to pricing JSON - [PR #20797](https://github.com/BerriAI/litellm/pull/20797)
|
||||
- Cleanup 39 deprecated OpenRouter models - [PR #20786](https://github.com/BerriAI/litellm/pull/20786)
|
||||
- Standardize endpoint `display_name` naming convention - [PR #20791](https://github.com/BerriAI/litellm/pull/20791)
|
||||
- Fix and stabilize model cost map formatting - [PR #20895](https://github.com/BerriAI/litellm/pull/20895)
|
||||
- Export `PermissionDeniedError` from `litellm.__init__` - [PR #20960](https://github.com/BerriAI/litellm/pull/20960)
|
||||
|
||||
### Bug Fixes
|
||||
|
||||
- **[Anthropic](../../docs/providers/anthropic)**
|
||||
- Fix `get_supported_anthropic_messages_params` - [PR #20752](https://github.com/BerriAI/litellm/pull/20752)
|
||||
- Fix `base_model` name for body and deployment name in URL - [PR #20747](https://github.com/BerriAI/litellm/pull/20747)
|
||||
|
||||
- **[Azure](../../docs/providers/azure/azure)**
|
||||
- Preserve `content_policy_violation` error details from Azure OpenAI - [PR #20883](https://github.com/BerriAI/litellm/pull/20883)
|
||||
|
||||
- **[Vertex AI](../../docs/providers/vertex)**
|
||||
- Fix Gemini multi-turn tool calling message formatting (added and reverted) - [PR #20569](https://github.com/BerriAI/litellm/pull/20569), [PR #21051](https://github.com/BerriAI/litellm/pull/21051)
|
||||
|
||||
---
|
||||
|
||||
## LLM API Endpoints
|
||||
|
||||
#### Features
|
||||
|
||||
- **[Responses API](../../docs/response_api)**
|
||||
- Add server-side context management (compaction) support - [PR #21058](https://github.com/BerriAI/litellm/pull/21058)
|
||||
- Add Shell tool support for OpenAI Responses API - [PR #21063](https://github.com/BerriAI/litellm/pull/21063)
|
||||
- Preserve tool call argument deltas when streaming id is omitted - [PR #20712](https://github.com/BerriAI/litellm/pull/20712)
|
||||
- Preserve interleaved thinking/redacted_thinking blocks during streaming - [PR #20702](https://github.com/BerriAI/litellm/pull/20702)
|
||||
|
||||
- **[Chat Completions](../../docs/completion/input)**
|
||||
- Add Web Search support using LiteLLM `/search` (web search interception hook) - [PR #20483](https://github.com/BerriAI/litellm/pull/20483)
|
||||
- Preserved nullable object fields by carrying schema properties - [PR #19132](https://github.com/BerriAI/litellm/pull/19132)
|
||||
- Support `prompt_cache_key` for OpenAI and Azure chat completions - [PR #20989](https://github.com/BerriAI/litellm/pull/20989)
|
||||
|
||||
- **[Pass-Through Endpoints](../../docs/pass_through/bedrock)**
|
||||
- Add support for `langchain_aws` via LiteLLM passthrough - [PR #20843](https://github.com/BerriAI/litellm/pull/20843)
|
||||
- Add `custom_body` parameter to `endpoint_func` in `create_pass_through_route` - [PR #20849](https://github.com/BerriAI/litellm/pull/20849)
|
||||
|
||||
- **[Vector Stores](../../docs/providers/openai)**
|
||||
- Add `target_model_names` for vector store endpoints - [PR #21089](https://github.com/BerriAI/litellm/pull/21089)
|
||||
|
||||
- **General**
|
||||
- Add `output_config` as supported param - [PR #20748](https://github.com/BerriAI/litellm/pull/20748)
|
||||
- Add managed error file support - [PR #20838](https://github.com/BerriAI/litellm/pull/20838)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- **General**
|
||||
- Stop leaking Python tracebacks in streaming SSE error responses - [PR #20850](https://github.com/BerriAI/litellm/pull/20850)
|
||||
- Fix video list pagination cursors not encoded with provider metadata - [PR #20710](https://github.com/BerriAI/litellm/pull/20710)
|
||||
- Handle `metadata=None` in SDK path retry/error logic - [PR #20873](https://github.com/BerriAI/litellm/pull/20873)
|
||||
- Fix Spend logs pickle error with Pydantic models and redaction - [PR #20685](https://github.com/BerriAI/litellm/pull/20685)
|
||||
- Remove duplicate `PerplexityResponsesConfig` from `LLM_CONFIG_NAMES` - [PR #21105](https://github.com/BerriAI/litellm/pull/21105)
|
||||
|
||||
---
|
||||
|
||||
## Management Endpoints / UI
|
||||
|
||||
#### Features
|
||||
|
||||
- **Access Groups**
|
||||
- New Access Groups feature for managing model, MCP server, and agent access - [PR #21022](https://github.com/BerriAI/litellm/pull/21022)
|
||||
- Access Groups table and details page UI - [PR #21165](https://github.com/BerriAI/litellm/pull/21165)
|
||||
- Refactor `model_ids` to `model_names` for backwards compatibility - [PR #21166](https://github.com/BerriAI/litellm/pull/21166)
|
||||
|
||||
- **Policies**
|
||||
- Allow connecting Policies to Tags, simulating Policies, viewing key/team counts - [PR #20904](https://github.com/BerriAI/litellm/pull/20904)
|
||||
- Guardrail pipeline support for conditional sequential execution - [PR #21177](https://github.com/BerriAI/litellm/pull/21177)
|
||||
- Pipeline flow builder UI for guardrail policies - [PR #21188](https://github.com/BerriAI/litellm/pull/21188)
|
||||
|
||||
- **SSO / Auth**
|
||||
- New Login With SSO Button - [PR #20908](https://github.com/BerriAI/litellm/pull/20908)
|
||||
- M2M OAuth2 UI Flow - [PR #20794](https://github.com/BerriAI/litellm/pull/20794)
|
||||
- Allow Organization and Team Admins to call `/invitation/new` - [PR #20987](https://github.com/BerriAI/litellm/pull/20987)
|
||||
- Invite User: Email Integration Alert - [PR #20790](https://github.com/BerriAI/litellm/pull/20790)
|
||||
- Populate identity fields in proxy admin JWT early-return path - [PR #21169](https://github.com/BerriAI/litellm/pull/21169)
|
||||
|
||||
- **Spend Logs**
|
||||
- Show predefined error codes in filter with user definable fallback - [PR #20773](https://github.com/BerriAI/litellm/pull/20773)
|
||||
- Paginated searchable model select - [PR #20892](https://github.com/BerriAI/litellm/pull/20892)
|
||||
- Sorting columns support - [PR #21143](https://github.com/BerriAI/litellm/pull/21143)
|
||||
- Allow sorting on `/spend/logs/ui` - [PR #20991](https://github.com/BerriAI/litellm/pull/20991)
|
||||
|
||||
- **UI Improvements**
|
||||
- Navbar: Option to hide Usage Popup - [PR #20910](https://github.com/BerriAI/litellm/pull/20910)
|
||||
- Model Page: Improve Credentials Messaging - [PR #21076](https://github.com/BerriAI/litellm/pull/21076)
|
||||
- Fallbacks: Default configurable to 10 models - [PR #21144](https://github.com/BerriAI/litellm/pull/21144)
|
||||
- Fallback display with arrows and card structure - [PR #20922](https://github.com/BerriAI/litellm/pull/20922)
|
||||
- Team Info: Migrate to AntD Tabs + Table - [PR #20785](https://github.com/BerriAI/litellm/pull/20785)
|
||||
- AntD refactoring and 0 cost models fix - [PR #20687](https://github.com/BerriAI/litellm/pull/20687)
|
||||
- Zscaler AI Guard UI - [PR #21077](https://github.com/BerriAI/litellm/pull/21077)
|
||||
- Include Config Defined Pass Through Endpoints - [PR #20898](https://github.com/BerriAI/litellm/pull/20898)
|
||||
- Rename "HTTP" to "Streamable HTTP (Recommended)" in MCP server page - [PR #21000](https://github.com/BerriAI/litellm/pull/21000)
|
||||
- MCP server discovery UI - [PR #21079](https://github.com/BerriAI/litellm/pull/21079)
|
||||
|
||||
- **Virtual Keys**
|
||||
- Allow Management keys to access `user/daily/activity` and team - [PR #20124](https://github.com/BerriAI/litellm/pull/20124)
|
||||
- Skip premium check for empty metadata fields on team/key update - [PR #20598](https://github.com/BerriAI/litellm/pull/20598)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- Logs: Fix Input and Output Copying - [PR #20657](https://github.com/BerriAI/litellm/pull/20657)
|
||||
- Teams: Fix Available Teams - [PR #20682](https://github.com/BerriAI/litellm/pull/20682)
|
||||
- Spend Logs: Reset Filters Resets Custom Date Range - [PR #21149](https://github.com/BerriAI/litellm/pull/21149)
|
||||
- Usage: Request Chart stack variant fix - [PR #20894](https://github.com/BerriAI/litellm/pull/20894)
|
||||
- Add Auto Router: Description Text Input Focus - [PR #21004](https://github.com/BerriAI/litellm/pull/21004)
|
||||
- Guardrail Edit: LiteLLM Content Filter Categories - [PR #21002](https://github.com/BerriAI/litellm/pull/21002)
|
||||
- Add null guard for models in API keys table - [PR #20655](https://github.com/BerriAI/litellm/pull/20655)
|
||||
- Show error details instead of 'Data Not Available' for failed requests - [PR #20656](https://github.com/BerriAI/litellm/pull/20656)
|
||||
- Fix Spend Management Tests - [PR #21088](https://github.com/BerriAI/litellm/pull/21088)
|
||||
- Fix JWT email domain validation error message - [PR #21212](https://github.com/BerriAI/litellm/pull/21212)
|
||||
|
||||
---
|
||||
|
||||
## AI Integrations
|
||||
|
||||
### Logging
|
||||
|
||||
- **[PostHog](../../docs/observability/posthog_integration)**
|
||||
- Fix JSON serialization error for non-serializable objects - [PR #20668](https://github.com/BerriAI/litellm/pull/20668)
|
||||
|
||||
- **[Prometheus](../../docs/proxy/logging#prometheus)**
|
||||
- Sanitize label values to prevent metric scrape failures - [PR #20600](https://github.com/BerriAI/litellm/pull/20600)
|
||||
|
||||
- **[Langfuse](../../docs/proxy/logging#langfuse)**
|
||||
- Prevent empty proxy request spans from being sent to Langfuse - [PR #19935](https://github.com/BerriAI/litellm/pull/19935)
|
||||
|
||||
- **[OpenTelemetry](../../docs/proxy/logging#otel)**
|
||||
- Auto-infer `otlp_http` exporter when endpoint is configured - [PR #20438](https://github.com/BerriAI/litellm/pull/20438)
|
||||
|
||||
- **[CloudZero](../../docs/proxy/logging)**
|
||||
- Update CBF field mappings per LIT-1907 - [PR #20906](https://github.com/BerriAI/litellm/pull/20906)
|
||||
|
||||
- **General**
|
||||
- Allow `MAX_CALLBACKS` override via env var - [PR #20781](https://github.com/BerriAI/litellm/pull/20781)
|
||||
- Add `standard_logging_payload_excluded_fields` config option - [PR #20831](https://github.com/BerriAI/litellm/pull/20831)
|
||||
- Enable `verbose_logger` when `LITELLM_LOG=DEBUG` - [PR #20496](https://github.com/BerriAI/litellm/pull/20496)
|
||||
- Guard against None `litellm_metadata` in batch logging path - [PR #20832](https://github.com/BerriAI/litellm/pull/20832)
|
||||
- Propagate model-level tags from config to SpendLogs - [PR #20769](https://github.com/BerriAI/litellm/pull/20769)
|
||||
|
||||
### Guardrails
|
||||
|
||||
- **Policy Templates**
|
||||
- New Policy Templates: pre-configured guardrail combinations for specific use-cases - [PR #21025](https://github.com/BerriAI/litellm/pull/21025)
|
||||
- Add NSFW policy template, toxic keywords in multiple languages, child safety content filter, JSON content viewer - [PR #21205](https://github.com/BerriAI/litellm/pull/21205)
|
||||
- Add toxic/abusive content filter guardrails - [PR #20934](https://github.com/BerriAI/litellm/pull/20934)
|
||||
|
||||
- **Pipeline Execution**
|
||||
- Add guardrail pipeline support for conditional sequential execution - [PR #21177](https://github.com/BerriAI/litellm/pull/21177)
|
||||
- Agent Guardrails on streaming output - [PR #21206](https://github.com/BerriAI/litellm/pull/21206)
|
||||
- Pipeline flow builder UI - [PR #21188](https://github.com/BerriAI/litellm/pull/21188)
|
||||
|
||||
- **[Zscaler AI Guard](../../docs/apply_guardrail)**
|
||||
- Zscaler AI Guard bug fixes and support during post-call - [PR #20801](https://github.com/BerriAI/litellm/pull/20801)
|
||||
- Zscaler AI Guard UI - [PR #21077](https://github.com/BerriAI/litellm/pull/21077)
|
||||
|
||||
- **[ZGuard](../../docs/apply_guardrail)**
|
||||
- Add team policy mapping for ZGuard - [PR #20608](https://github.com/BerriAI/litellm/pull/20608)
|
||||
|
||||
- **General**
|
||||
- Add logging to all unified guardrails + link to custom code guardrail templates - [PR #20900](https://github.com/BerriAI/litellm/pull/20900)
|
||||
- Forward request headers + `litellm_version` to generic guardrails - [PR #20729](https://github.com/BerriAI/litellm/pull/20729)
|
||||
- Empty `guardrails`/`policies` arrays should not trigger enterprise license check - [PR #20567](https://github.com/BerriAI/litellm/pull/20567)
|
||||
- Fix OpenAI moderation guardrails - [PR #20718](https://github.com/BerriAI/litellm/pull/20718)
|
||||
- Fix `/v2/guardrails/list` returning sensitive values - [PR #20796](https://github.com/BerriAI/litellm/pull/20796)
|
||||
- Fix guardrail status error - [PR #20972](https://github.com/BerriAI/litellm/pull/20972)
|
||||
- Reuse `get_instance_fn` in `initialize_custom_guardrail` - [PR #20917](https://github.com/BerriAI/litellm/pull/20917)
|
||||
|
||||
---
|
||||
|
||||
## Spend Tracking, Budgets and Rate Limiting
|
||||
|
||||
- **Prevent shared backend model key from being polluted** by per-deployment custom pricing - [PR #20679](https://github.com/BerriAI/litellm/pull/20679)
|
||||
- **Avoid in-place mutation** in SpendUpdateQueue aggregation - [PR #20876](https://github.com/BerriAI/litellm/pull/20876)
|
||||
|
||||
---
|
||||
|
||||
## MCP Gateway (12 updates)
|
||||
|
||||
- **MCP M2M OAuth2 Support** - Add support for machine-to-machine OAuth2 for MCP servers - [PR #20788](https://github.com/BerriAI/litellm/pull/20788)
|
||||
- **MCP Server Discovery UI** - Browse and discover available MCP servers from the UI - [PR #21079](https://github.com/BerriAI/litellm/pull/21079)
|
||||
- **MCP Tracing** - Add OpenTelemetry tracing for MCP calls running through AI Gateway - [PR #21018](https://github.com/BerriAI/litellm/pull/21018)
|
||||
- **MCP OAuth2 Debug Headers** - Client-side debug headers for OAuth2 troubleshooting - [PR #21151](https://github.com/BerriAI/litellm/pull/21151)
|
||||
- **Fix MCP "Session not found" errors** - Resolve session persistence issues - [PR #21040](https://github.com/BerriAI/litellm/pull/21040)
|
||||
- **Fix MCP OAuth2 root endpoints** returning "MCP server not found" - [PR #20784](https://github.com/BerriAI/litellm/pull/20784)
|
||||
- **Fix MCP OAuth2 query param merging** when `authorization_url` already contains params - [PR #20968](https://github.com/BerriAI/litellm/pull/20968)
|
||||
- **Fix MCP SCOPES on Atlassian** issue - [PR #21150](https://github.com/BerriAI/litellm/pull/21150)
|
||||
- **Fix MCP StreamableHTTP backend** - Use `anyio.fail_after` instead of `asyncio.wait_for` - [PR #20891](https://github.com/BerriAI/litellm/pull/20891)
|
||||
- **Inject `NPM_CONFIG_CACHE`** into STDIO MCP subprocess env - [PR #21069](https://github.com/BerriAI/litellm/pull/21069)
|
||||
- **Block spaces and hyphens** in MCP server names and aliases - [PR #21074](https://github.com/BerriAI/litellm/pull/21074)
|
||||
|
||||
---
|
||||
|
||||
## Performance / Loadbalancing / Reliability improvements (8 improvements)
|
||||
|
||||
- **Remove orphan entries from queue** - Fix memory leak in scheduler queue - [PR #20866](https://github.com/BerriAI/litellm/pull/20866)
|
||||
- **Remove repeated provider parsing** in budget limiter hot path - [PR #21043](https://github.com/BerriAI/litellm/pull/21043)
|
||||
- **Use current retry exception** for retry backoff instead of stale exception - [PR #20725](https://github.com/BerriAI/litellm/pull/20725)
|
||||
- **Add Semgrep & fix OOMs** - Static analysis rules and out-of-memory fixes - [PR #20912](https://github.com/BerriAI/litellm/pull/20912)
|
||||
- **Add Pyroscope** for continuous profiling and observability - [PR #21167](https://github.com/BerriAI/litellm/pull/21167)
|
||||
- **Respect `ssl_verify`** with shared aiohttp sessions - [PR #20349](https://github.com/BerriAI/litellm/pull/20349)
|
||||
- **Fix shared health check serialization** - [PR #21119](https://github.com/BerriAI/litellm/pull/21119)
|
||||
- **Change model mismatch logs** from WARNING to DEBUG - [PR #20994](https://github.com/BerriAI/litellm/pull/20994)
|
||||
|
||||
---
|
||||
|
||||
## Database Changes
|
||||
|
||||
### Schema Updates
|
||||
|
||||
| Table | Change Type | Description | PR | Migration |
|
||||
| ----- | ----------- | ----------- | -- | --------- |
|
||||
| `LiteLLM_VerificationToken` | New Indexes | Added indexes on `user_id`+`team_id`, `team_id`, and `budget_reset_at`+`expires` | [PR #20736](https://github.com/BerriAI/litellm/pull/20736) | [Migration](https://github.com/BerriAI/litellm/blob/main/litellm-proxy-extras/litellm_proxy_extras/migrations/20260209085821_add_verificationtoken_indexes/migration.sql) |
|
||||
| `LiteLLM_PolicyAttachmentTable` | New Column | Added `tags` text array for policy-to-tag connections | [PR #21061](https://github.com/BerriAI/litellm/pull/21061) | [Migration](https://github.com/BerriAI/litellm/blob/main/litellm-proxy-extras/litellm_proxy_extras/migrations/20260212103349_adjust_tags_policy_table/migration.sql) |
|
||||
| `LiteLLM_AccessGroupTable` | New Table | Access groups for managing model, MCP server, and agent access | [PR #21022](https://github.com/BerriAI/litellm/pull/21022) | [Migration](https://github.com/BerriAI/litellm/blob/main/litellm-proxy-extras/litellm_proxy_extras/migrations/20260212143306_add_access_group_table/migration.sql) |
|
||||
| `LiteLLM_AccessGroupTable` | Column Change | Renamed `access_model_ids` to `access_model_names` | [PR #21166](https://github.com/BerriAI/litellm/pull/21166) | [Migration](https://github.com/BerriAI/litellm/blob/main/litellm-proxy-extras/litellm_proxy_extras/migrations/20260213170952_access_group_change_to_model_name/migration.sql) |
|
||||
| `LiteLLM_ManagedVectorStoreTable` | New Table | Managed vector store tracking with model mappings | - | [Migration](https://github.com/BerriAI/litellm/blob/main/litellm-proxy-extras/litellm_proxy_extras/migrations/20260213105436_add_managed_vector_store_table/migration.sql) |
|
||||
| `LiteLLM_TeamTable`, `LiteLLM_VerificationToken` | New Column | Added `access_group_ids` text array | [PR #21022](https://github.com/BerriAI/litellm/pull/21022) | [Migration](https://github.com/BerriAI/litellm/blob/main/litellm-proxy-extras/litellm_proxy_extras/migrations/20260212143306_add_access_group_table/migration.sql) |
|
||||
| `LiteLLM_GuardrailsTable` | New Column | Added `team_id` text column | - | [Migration](https://github.com/BerriAI/litellm/blob/main/litellm-proxy-extras/litellm_proxy_extras/migrations/20260214094754_schema_sync/migration.sql) |
|
||||
|
||||
---
|
||||
|
||||
## Documentation Updates (14 updates)
|
||||
|
||||
- LiteLLM Observatory section added to v1.81.9 release notes - [PR #20675](https://github.com/BerriAI/litellm/pull/20675)
|
||||
- Callback registration optimization added to release notes - [PR #20681](https://github.com/BerriAI/litellm/pull/20681)
|
||||
- Middleware performance blog post - [PR #20677](https://github.com/BerriAI/litellm/pull/20677)
|
||||
- UI Team Soft Budget documentation - [PR #20669](https://github.com/BerriAI/litellm/pull/20669)
|
||||
- UI Contributing and Troubleshooting guide - [PR #20674](https://github.com/BerriAI/litellm/pull/20674)
|
||||
- Reorganize Admin UI subsection - [PR #20676](https://github.com/BerriAI/litellm/pull/20676)
|
||||
- SDK proxy authentication (OAuth2/JWT auto-refresh) - [PR #20680](https://github.com/BerriAI/litellm/pull/20680)
|
||||
- Forward client headers to LLM API documentation fix - [PR #20768](https://github.com/BerriAI/litellm/pull/20768)
|
||||
- Add docs guide for using policies - [PR #20914](https://github.com/BerriAI/litellm/pull/20914)
|
||||
- Add native thinking param examples for Claude Opus 4.6 - [PR #20799](https://github.com/BerriAI/litellm/pull/20799)
|
||||
- Fix Claude Code MCP tutorial - [PR #21145](https://github.com/BerriAI/litellm/pull/21145)
|
||||
- Add API base URLs for Dashscope (International and China/Beijing) - [PR #21083](https://github.com/BerriAI/litellm/pull/21083)
|
||||
- Fix `DEFAULT_NUM_WORKERS_LITELLM_PROXY` default (1, not 4) - [PR #21127](https://github.com/BerriAI/litellm/pull/21127)
|
||||
- Correct ElevenLabs support status in README - [PR #20643](https://github.com/BerriAI/litellm/pull/20643)
|
||||
|
||||
---
|
||||
|
||||
## New Contributors
|
||||
* @iver56 made their first contribution in [PR #20643](https://github.com/BerriAI/litellm/pull/20643)
|
||||
* @eliasaronson made their first contribution in [PR #20666](https://github.com/BerriAI/litellm/pull/20666)
|
||||
* @NirantK made their first contribution in [PR #19656](https://github.com/BerriAI/litellm/pull/19656)
|
||||
* @looksgood made their first contribution in [PR #20919](https://github.com/BerriAI/litellm/pull/20919)
|
||||
* @kelvin-tran made their first contribution in [PR #20548](https://github.com/BerriAI/litellm/pull/20548)
|
||||
* @bluet made their first contribution in [PR #20873](https://github.com/BerriAI/litellm/pull/20873)
|
||||
* @itayov made their first contribution in [PR #20729](https://github.com/BerriAI/litellm/pull/20729)
|
||||
* @CSteigstra made their first contribution in [PR #20960](https://github.com/BerriAI/litellm/pull/20960)
|
||||
* @rahulrd25 made their first contribution in [PR #20569](https://github.com/BerriAI/litellm/pull/20569)
|
||||
* @muraliavarma made their first contribution in [PR #20598](https://github.com/BerriAI/litellm/pull/20598)
|
||||
* @joaokopernico made their first contribution in [PR #21039](https://github.com/BerriAI/litellm/pull/21039)
|
||||
* @datzscaler made their first contribution in [PR #21077](https://github.com/BerriAI/litellm/pull/21077)
|
||||
* @atapia27 made their first contribution in [PR #20922](https://github.com/BerriAI/litellm/pull/20922)
|
||||
* @fpagny made their first contribution in [PR #21121](https://github.com/BerriAI/litellm/pull/21121)
|
||||
* @aidankovacic-8451 made their first contribution in [PR #21119](https://github.com/BerriAI/litellm/pull/21119)
|
||||
* @luisgallego-aily made their first contribution in [PR #19935](https://github.com/BerriAI/litellm/pull/19935)
|
||||
|
||||
---
|
||||
|
||||
## Full Changelog
|
||||
[v1.81.9.rc.1...v1.81.12.rc.1](https://github.com/BerriAI/litellm/compare/v1.81.9.rc.1...v1.81.12.rc.1)
|
||||
|
|
@ -14,6 +14,14 @@ authors:
|
|||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
:::danger Known Issue - CPU Usage
|
||||
|
||||
This release had known issues with CPU usage. This has been fixed in [v1.81.9-stable](./v1-81-9).
|
||||
|
||||
**We recommend using v1.81.9-stable instead.**
|
||||
|
||||
:::
|
||||
|
||||
## Deploy this version
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
|
|
|
|||
|
|
@ -1,5 +1,5 @@
|
|||
---
|
||||
title: "[Preview] v1.81.9 - Control which MCP Servers are exposed on the Internet"
|
||||
title: "v1.81.9 - Control which MCP Servers are exposed on the Internet"
|
||||
slug: "v1-81-9"
|
||||
date: 2026-02-07T00:00:00
|
||||
authors:
|
||||
|
|
@ -14,6 +14,16 @@ authors:
|
|||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
:::info Stable Release Branch
|
||||
|
||||
For each stable release, we now maintain a dedicated branch with the format `litellm_stable_release_branch_x_xx_xx` for the version.
|
||||
|
||||
This allows easier patching for day 0 model launches.
|
||||
|
||||
**Branch for v1.81.9:** [litellm_stable_release_branch_1_81_9](https://github.com/BerriAI/litellm/tree/litellm_stable_release_branch_1_81_9)
|
||||
|
||||
:::
|
||||
|
||||
## Deploy this version
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
|
|
@ -27,7 +37,7 @@ import Image from '@theme/IdealImage';
|
|||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
ghcr.io/berriai/litellm:main-v1.81.9.rc.1
|
||||
ghcr.io/berriai/litellm:main-v1.81.9-stable
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
|
|
|||
|
|
@ -42,49 +42,63 @@ const sidebars = {
|
|||
label: "Guardrails",
|
||||
items: [
|
||||
"proxy/guardrails/quick_start",
|
||||
"proxy/guardrails/guardrail_policies",
|
||||
"proxy/guardrails/guardrail_load_balancing",
|
||||
"proxy/guardrails/test_playground",
|
||||
"proxy/guardrails/litellm_content_filter",
|
||||
{
|
||||
type: "category",
|
||||
"label": "Contributing to Guardrails",
|
||||
label: "Providers",
|
||||
items: [
|
||||
...[
|
||||
"proxy/guardrails/qualifire",
|
||||
"proxy/guardrails/aim_security",
|
||||
"proxy/guardrails/onyx_security",
|
||||
"proxy/guardrails/aporia_api",
|
||||
"proxy/guardrails/azure_content_guardrail",
|
||||
"proxy/guardrails/bedrock",
|
||||
"proxy/guardrails/enkryptai",
|
||||
"proxy/guardrails/ibm_guardrails",
|
||||
"proxy/guardrails/grayswan",
|
||||
"proxy/guardrails/hiddenlayer",
|
||||
"proxy/guardrails/lasso_security",
|
||||
"proxy/guardrails/guardrails_ai",
|
||||
"proxy/guardrails/lakera_ai",
|
||||
"proxy/guardrails/model_armor",
|
||||
"proxy/guardrails/noma_security",
|
||||
"proxy/guardrails/dynamoai",
|
||||
"proxy/guardrails/openai_moderation",
|
||||
"proxy/guardrails/pangea",
|
||||
"proxy/guardrails/pillar_security",
|
||||
"proxy/guardrails/pii_masking_v2",
|
||||
"proxy/guardrails/panw_prisma_airs",
|
||||
"proxy/guardrails/secret_detection",
|
||||
"proxy/guardrails/custom_guardrail",
|
||||
"proxy/guardrails/custom_code_guardrail",
|
||||
"proxy/guardrails/prompt_injection",
|
||||
"proxy/guardrails/tool_permission",
|
||||
"proxy/guardrails/zscaler_ai_guard",
|
||||
"proxy/guardrails/javelin"
|
||||
].sort(),
|
||||
],
|
||||
},
|
||||
{
|
||||
type: "category",
|
||||
label: "Contributing to Guardrails",
|
||||
items: [
|
||||
"adding_provider/generic_guardrail_api",
|
||||
"adding_provider/simple_guardrail_tutorial",
|
||||
"adding_provider/adding_guardrail_support",
|
||||
]
|
||||
},
|
||||
"proxy/guardrails/test_playground",
|
||||
"proxy/guardrails/litellm_content_filter",
|
||||
...[
|
||||
"proxy/guardrails/qualifire",
|
||||
"proxy/guardrails/aim_security",
|
||||
"proxy/guardrails/onyx_security",
|
||||
"proxy/guardrails/aporia_api",
|
||||
"proxy/guardrails/azure_content_guardrail",
|
||||
"proxy/guardrails/bedrock",
|
||||
"proxy/guardrails/enkryptai",
|
||||
"proxy/guardrails/ibm_guardrails",
|
||||
"proxy/guardrails/grayswan",
|
||||
"proxy/guardrails/hiddenlayer",
|
||||
"proxy/guardrails/lasso_security",
|
||||
"proxy/guardrails/guardrails_ai",
|
||||
"proxy/guardrails/lakera_ai",
|
||||
"proxy/guardrails/model_armor",
|
||||
"proxy/guardrails/noma_security",
|
||||
"proxy/guardrails/dynamoai",
|
||||
"proxy/guardrails/openai_moderation",
|
||||
"proxy/guardrails/pangea",
|
||||
"proxy/guardrails/pillar_security",
|
||||
"proxy/guardrails/pii_masking_v2",
|
||||
"proxy/guardrails/panw_prisma_airs",
|
||||
"proxy/guardrails/secret_detection",
|
||||
"proxy/guardrails/custom_guardrail",
|
||||
"proxy/guardrails/custom_code_guardrail",
|
||||
"proxy/guardrails/prompt_injection",
|
||||
"proxy/guardrails/tool_permission",
|
||||
"proxy/guardrails/zscaler_ai_guard",
|
||||
"proxy/guardrails/javelin"
|
||||
].sort(),
|
||||
],
|
||||
},
|
||||
{
|
||||
type: "category",
|
||||
label: "Policies",
|
||||
items: [
|
||||
"proxy/guardrails/guardrail_policies",
|
||||
"proxy/guardrails/policy_templates",
|
||||
"proxy/guardrails/policy_tags",
|
||||
],
|
||||
},
|
||||
{
|
||||
|
|
@ -93,7 +107,8 @@ const sidebars = {
|
|||
items: [
|
||||
"proxy/alerting",
|
||||
"proxy/pagerduty",
|
||||
"proxy/prometheus"
|
||||
"proxy/prometheus",
|
||||
"proxy/pyroscope_profiling"
|
||||
]
|
||||
},
|
||||
{
|
||||
|
|
@ -161,6 +176,7 @@ const sidebars = {
|
|||
"tutorials/copilotkit_sdk",
|
||||
"tutorials/google_adk",
|
||||
"tutorials/livekit_xai_realtime",
|
||||
"projects/openai-agents"
|
||||
]
|
||||
},
|
||||
|
||||
|
|
@ -396,6 +412,16 @@ const sidebars = {
|
|||
],
|
||||
},
|
||||
"proxy/caching",
|
||||
{
|
||||
type: "link",
|
||||
label: "Guardrails",
|
||||
href: "https://docs.litellm.ai/docs/proxy/guardrails/quick_start",
|
||||
},
|
||||
{
|
||||
type: "link",
|
||||
label: "Policies",
|
||||
href: "https://docs.litellm.ai/docs/proxy/guardrails/guardrail_policies",
|
||||
},
|
||||
{
|
||||
type: "category",
|
||||
label: "Create Custom Plugins",
|
||||
|
|
@ -442,6 +468,7 @@ const sidebars = {
|
|||
"proxy/model_access_guide",
|
||||
"proxy/model_access",
|
||||
"proxy/model_access_groups",
|
||||
"proxy/access_groups",
|
||||
"proxy/team_model_add"
|
||||
]
|
||||
},
|
||||
|
|
@ -850,6 +877,7 @@ const sidebars = {
|
|||
},
|
||||
"providers/sambanova",
|
||||
"providers/sap",
|
||||
"providers/scaleway",
|
||||
"providers/stability",
|
||||
"providers/synthetic",
|
||||
"providers/snowflake",
|
||||
|
|
@ -979,6 +1007,7 @@ const sidebars = {
|
|||
"tutorials/presidio_pii_masking",
|
||||
"tutorials/elasticsearch_logging",
|
||||
"tutorials/gemini_realtime_with_audio",
|
||||
"tutorials/claude_code_beta_headers",
|
||||
{
|
||||
type: "category",
|
||||
label: "LiteLLM Python SDK Tutorials",
|
||||
|
|
@ -1073,16 +1102,24 @@ const sidebars = {
|
|||
"proxy_server",
|
||||
],
|
||||
},
|
||||
"troubleshoot",
|
||||
{
|
||||
type: "category",
|
||||
label: "Issue Reporting",
|
||||
label: "Troubleshooting",
|
||||
items: [
|
||||
"troubleshoot/prisma_migrations",
|
||||
"troubleshoot/cpu_issues",
|
||||
"troubleshoot/memory_issues",
|
||||
"troubleshoot/spend_queue_warnings",
|
||||
"troubleshoot/max_callbacks",
|
||||
"troubleshoot/ui_issues",
|
||||
"mcp_troubleshoot",
|
||||
{
|
||||
type: "category",
|
||||
label: "Performance / Latency",
|
||||
items: [
|
||||
"troubleshoot/cpu_issues",
|
||||
"troubleshoot/memory_issues",
|
||||
"troubleshoot/spend_queue_warnings",
|
||||
"troubleshoot/max_callbacks",
|
||||
"troubleshoot/prisma_migrations",
|
||||
],
|
||||
},
|
||||
"troubleshoot",
|
||||
],
|
||||
},
|
||||
{
|
||||
|
|
|
|||
BIN
enterprise/dist/litellm_enterprise-0.1.32-py3-none-any.whl
vendored
Normal file
BIN
enterprise/dist/litellm_enterprise-0.1.32-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
enterprise/dist/litellm_enterprise-0.1.32.tar.gz
vendored
Normal file
BIN
enterprise/dist/litellm_enterprise-0.1.32.tar.gz
vendored
Normal file
Binary file not shown.
|
|
@ -1,11 +1,15 @@
|
|||
from typing import Dict, Literal, Type, Union
|
||||
|
||||
from litellm_enterprise.proxy.hooks.managed_files import _PROXY_LiteLLMManagedFiles
|
||||
from litellm_enterprise.proxy.hooks.managed_vector_stores import (
|
||||
_PROXY_LiteLLMManagedVectorStores,
|
||||
)
|
||||
|
||||
from litellm.integrations.custom_logger import CustomLogger
|
||||
|
||||
ENTERPRISE_PROXY_HOOKS: Dict[str, Type[CustomLogger]] = {
|
||||
"managed_files": _PROXY_LiteLLMManagedFiles,
|
||||
"managed_vector_stores": _PROXY_LiteLLMManagedVectorStores,
|
||||
}
|
||||
|
||||
|
||||
|
|
@ -13,6 +17,7 @@ def get_enterprise_proxy_hook(
|
|||
hook_name: Union[
|
||||
Literal[
|
||||
"managed_files",
|
||||
"managed_vector_stores",
|
||||
"max_parallel_requests",
|
||||
],
|
||||
str,
|
||||
|
|
|
|||
|
|
@ -41,6 +41,10 @@ class EnterpriseRouteChecks:
|
|||
|
||||
return get_secret_bool("DISABLE_ADMIN_ENDPOINTS") is True
|
||||
|
||||
# Routes that should remain accessible even when LLM API endpoints are disabled.
|
||||
# These are read-only model listing routes needed by the Admin UI.
|
||||
LLM_API_EXEMPT_ROUTES = ["/models", "/v1/models"]
|
||||
|
||||
@staticmethod
|
||||
def should_call_route(route: str):
|
||||
"""
|
||||
|
|
@ -58,6 +62,7 @@ class EnterpriseRouteChecks:
|
|||
)
|
||||
elif (
|
||||
RouteChecks.is_llm_api_route(route=route)
|
||||
and route not in EnterpriseRouteChecks.LLM_API_EXEMPT_ROUTES
|
||||
and EnterpriseRouteChecks.is_llm_api_route_disabled()
|
||||
):
|
||||
raise HTTPException(
|
||||
|
|
|
|||
|
|
@ -4,7 +4,7 @@ Polls LiteLLM_ManagedObjectTable to check if the batch job is complete, and if t
|
|||
|
||||
from litellm._uuid import uuid
|
||||
from datetime import datetime
|
||||
from typing import TYPE_CHECKING, Optional, cast
|
||||
from typing import TYPE_CHECKING, Optional
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
|
||||
|
|
@ -35,14 +35,11 @@ class CheckBatchCost:
|
|||
- if not, return False
|
||||
- if so, return True
|
||||
"""
|
||||
from litellm_enterprise.proxy.hooks.managed_files import (
|
||||
_PROXY_LiteLLMManagedFiles,
|
||||
)
|
||||
|
||||
from litellm.batches.batch_utils import (
|
||||
_get_file_content_as_dictionary,
|
||||
calculate_batch_cost_and_usage,
|
||||
)
|
||||
from litellm.files.main import afile_content
|
||||
from litellm.litellm_core_utils.get_llm_provider_logic import get_llm_provider
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLogging
|
||||
from litellm.proxy.openai_files_endpoints.common_utils import (
|
||||
|
|
@ -102,27 +99,29 @@ class CheckBatchCost:
|
|||
continue
|
||||
|
||||
## RETRIEVE THE BATCH JOB OUTPUT FILE
|
||||
managed_files_obj = cast(
|
||||
Optional[_PROXY_LiteLLMManagedFiles],
|
||||
self.proxy_logging_obj.get_proxy_hook("managed_files"),
|
||||
)
|
||||
if (
|
||||
response.status == "completed"
|
||||
and response.output_file_id is not None
|
||||
and managed_files_obj is not None
|
||||
):
|
||||
verbose_proxy_logger.info(
|
||||
f"Batch ID: {batch_id} is complete, tracking cost and usage"
|
||||
)
|
||||
# track cost
|
||||
model_file_id_mapping = {
|
||||
response.output_file_id: {model_id: response.output_file_id}
|
||||
}
|
||||
_file_content = await managed_files_obj.afile_content(
|
||||
file_id=response.output_file_id,
|
||||
litellm_parent_otel_span=None,
|
||||
llm_router=self.llm_router,
|
||||
model_file_id_mapping=model_file_id_mapping,
|
||||
|
||||
# This background job runs as default_user_id, so going through the HTTP endpoint
|
||||
# would trigger check_managed_file_id_access and get 403. Instead, extract the raw
|
||||
# provider file ID and call afile_content directly with deployment credentials.
|
||||
raw_output_file_id = response.output_file_id
|
||||
decoded = _is_base64_encoded_unified_file_id(raw_output_file_id)
|
||||
if decoded:
|
||||
try:
|
||||
raw_output_file_id = decoded.split("llm_output_file_id,")[1].split(";")[0]
|
||||
except (IndexError, AttributeError):
|
||||
pass
|
||||
|
||||
credentials = self.llm_router.get_deployment_credentials_with_provider(model_id) or {}
|
||||
_file_content = await afile_content(
|
||||
file_id=raw_output_file_id,
|
||||
**credentials,
|
||||
)
|
||||
|
||||
file_content_as_dict = _get_file_content_as_dictionary(
|
||||
|
|
@ -143,11 +142,15 @@ class CheckBatchCost:
|
|||
custom_llm_provider=custom_llm_provider,
|
||||
)
|
||||
|
||||
# Pass deployment model_info so custom batch pricing
|
||||
# (input_cost_per_token_batches etc.) is used for cost calc
|
||||
deployment_model_info = deployment_info.model_info.model_dump() if deployment_info.model_info else {}
|
||||
batch_cost, batch_usage, batch_models = (
|
||||
await calculate_batch_cost_and_usage(
|
||||
file_content_dictionary=file_content_as_dict,
|
||||
custom_llm_provider=llm_provider, # type: ignore
|
||||
model_name=model_name,
|
||||
model_info=deployment_model_info,
|
||||
)
|
||||
)
|
||||
logging_obj = LiteLLMLogging(
|
||||
|
|
|
|||
|
|
@ -230,12 +230,14 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
|
||||
if managed_file:
|
||||
return managed_file.created_by == user_id
|
||||
return False
|
||||
raise HTTPException(
|
||||
status_code=404,
|
||||
detail=f"File not found: {unified_file_id}",
|
||||
)
|
||||
|
||||
async def can_user_call_unified_object_id(
|
||||
self, unified_object_id: str, user_api_key_dict: UserAPIKeyAuth
|
||||
) -> bool:
|
||||
## check if the user has access to the unified object id
|
||||
## check if the user has access to the unified object id
|
||||
user_id = user_api_key_dict.user_id
|
||||
managed_object = (
|
||||
|
|
@ -246,7 +248,10 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
|
||||
if managed_object:
|
||||
return managed_object.created_by == user_id
|
||||
return True # don't raise error if managed object is not found
|
||||
raise HTTPException(
|
||||
status_code=404,
|
||||
detail=f"Object not found: {unified_object_id}",
|
||||
)
|
||||
|
||||
async def list_user_batches(
|
||||
self,
|
||||
|
|
@ -911,15 +916,22 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
)
|
||||
setattr(response, file_attr, unified_file_id)
|
||||
|
||||
# Fetch the actual file object from the provider
|
||||
# Use llm_router credentials when available. Without credentials,
|
||||
# Azure and other auth-required providers return 500/401.
|
||||
file_object = None
|
||||
try:
|
||||
# Use litellm to retrieve the file object from the provider
|
||||
from litellm import afile_retrieve
|
||||
file_object = await afile_retrieve(
|
||||
custom_llm_provider=model_name.split("/")[0] if model_name and "/" in model_name else "openai",
|
||||
file_id=original_file_id
|
||||
)
|
||||
from litellm.proxy.proxy_server import llm_router as _llm_router
|
||||
if _llm_router is not None and model_id:
|
||||
_creds = _llm_router.get_deployment_credentials_with_provider(model_id) or {}
|
||||
file_object = await litellm.afile_retrieve(
|
||||
file_id=original_file_id,
|
||||
**_creds,
|
||||
)
|
||||
else:
|
||||
file_object = await litellm.afile_retrieve(
|
||||
custom_llm_provider=model_name.split("/")[0] if model_name and "/" in model_name else "openai",
|
||||
file_id=original_file_id,
|
||||
)
|
||||
verbose_logger.debug(
|
||||
f"Successfully retrieved file object for {file_attr}={original_file_id}"
|
||||
)
|
||||
|
|
@ -1004,7 +1016,10 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
raise Exception(f"LiteLLM Managed File object with id={file_id} not found")
|
||||
|
||||
# Case 2: Managed file and the file object exists in the database
|
||||
# The stored file_object has the raw provider ID. Replace with the unified ID
|
||||
# so callers see a consistent ID (matching Case 3 which does response.id = file_id).
|
||||
if stored_file_object and stored_file_object.file_object:
|
||||
stored_file_object.file_object.id = file_id
|
||||
return stored_file_object.file_object
|
||||
|
||||
# Case 3: Managed file exists in the database but not the file object (for. e.g the batch task might not have run)
|
||||
|
|
|
|||
|
|
@ -0,0 +1,464 @@
|
|||
# What is this?
|
||||
## This hook is used to manage vector stores with target_model_names support
|
||||
## It allows creating vector stores across multiple models and managing them with unified IDs
|
||||
|
||||
from typing import TYPE_CHECKING, Any, Dict, List, Optional, Union, cast
|
||||
|
||||
from fastapi import HTTPException
|
||||
|
||||
import litellm
|
||||
from litellm import Router, verbose_logger
|
||||
from litellm._uuid import uuid
|
||||
from litellm.integrations.custom_logger import CustomLogger
|
||||
from litellm.llms.base_llm.managed_resources import BaseManagedResource
|
||||
from litellm.llms.base_llm.managed_resources.utils import (
|
||||
generate_unified_id_string,
|
||||
is_base64_encoded_unified_id,
|
||||
)
|
||||
from litellm.proxy._types import UserAPIKeyAuth
|
||||
from litellm.types.vector_stores import (
|
||||
VectorStoreCreateOptionalRequestParams,
|
||||
VectorStoreCreateResponse,
|
||||
)
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from opentelemetry.trace import Span as _Span
|
||||
|
||||
from litellm.proxy.utils import InternalUsageCache as _InternalUsageCache
|
||||
from litellm.proxy.utils import PrismaClient as _PrismaClient
|
||||
|
||||
Span = Union[_Span, Any]
|
||||
InternalUsageCache = _InternalUsageCache
|
||||
PrismaClient = _PrismaClient
|
||||
else:
|
||||
Span = Any
|
||||
InternalUsageCache = Any
|
||||
PrismaClient = Any
|
||||
|
||||
|
||||
class _PROXY_LiteLLMManagedVectorStores(
|
||||
CustomLogger, BaseManagedResource[VectorStoreCreateResponse]
|
||||
):
|
||||
"""
|
||||
Managed vector stores with target_model_names support.
|
||||
|
||||
This class provides functionality to:
|
||||
- Create vector stores across multiple models
|
||||
- Retrieve vector stores by unified ID
|
||||
- Delete vector stores from all models
|
||||
- List vector stores created by a user
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self, internal_usage_cache: InternalUsageCache, prisma_client: PrismaClient
|
||||
):
|
||||
CustomLogger.__init__(self)
|
||||
BaseManagedResource.__init__(self, internal_usage_cache, prisma_client)
|
||||
|
||||
# ============================================================================
|
||||
# ABSTRACT METHOD IMPLEMENTATIONS
|
||||
# ============================================================================
|
||||
|
||||
@property
|
||||
def resource_type(self) -> str:
|
||||
"""Return the resource type identifier."""
|
||||
return "vector_store"
|
||||
|
||||
@property
|
||||
def table_name(self) -> str:
|
||||
"""Return the database table name for vector stores."""
|
||||
# Prisma converts model name LiteLLM_ManagedVectorStoreTable to litellm_managedvectorstoretable
|
||||
return "litellm_managedvectorstoretable"
|
||||
|
||||
def get_unified_resource_id_format(
|
||||
self,
|
||||
resource_object: VectorStoreCreateResponse,
|
||||
target_model_names_list: List[str],
|
||||
) -> str:
|
||||
"""
|
||||
Generate the format string for the unified vector store ID.
|
||||
|
||||
Format:
|
||||
litellm_proxy:vector_store;unified_id,<uuid>;target_model_names,<models>;resource_id,<vs_id>;model_id,<model_id>
|
||||
"""
|
||||
# VectorStoreCreateResponse is a TypedDict, so resource_object is a dictionary
|
||||
# Extract provider resource ID from the response
|
||||
provider_resource_id = resource_object.get("id", "")
|
||||
|
||||
# Model ID is stored in hidden params if the response object supports it
|
||||
# For TypedDict responses, we need to check if _hidden_params was added
|
||||
hidden_params: Dict[str, Any] = {}
|
||||
if hasattr(resource_object, "_hidden_params"):
|
||||
hidden_params = getattr(resource_object, "_hidden_params", {}) or {}
|
||||
model_id = hidden_params.get("model_id", "")
|
||||
|
||||
return generate_unified_id_string(
|
||||
resource_type=self.resource_type,
|
||||
unified_uuid=str(uuid.uuid4()),
|
||||
target_model_names=target_model_names_list,
|
||||
provider_resource_id=provider_resource_id,
|
||||
model_id=model_id,
|
||||
)
|
||||
|
||||
async def create_resource_for_model(
|
||||
self,
|
||||
llm_router: Router,
|
||||
model: str,
|
||||
request_data: Dict[str, Any],
|
||||
litellm_parent_otel_span: Span,
|
||||
) -> VectorStoreCreateResponse:
|
||||
"""
|
||||
Create a vector store for a specific model.
|
||||
|
||||
Args:
|
||||
llm_router: LiteLLM router instance
|
||||
model: Model name to create vector store for
|
||||
request_data: Request data for vector store creation
|
||||
litellm_parent_otel_span: OpenTelemetry span for tracing
|
||||
|
||||
Returns:
|
||||
VectorStoreCreateResponse from the provider
|
||||
"""
|
||||
# Use the router to create the vector store
|
||||
response = await llm_router.avector_store_create(
|
||||
model=model, **request_data
|
||||
)
|
||||
return response
|
||||
|
||||
# ============================================================================
|
||||
# VECTOR STORE CRUD OPERATIONS
|
||||
# ============================================================================
|
||||
|
||||
async def acreate_vector_store(
|
||||
self,
|
||||
create_request: VectorStoreCreateOptionalRequestParams,
|
||||
llm_router: Router,
|
||||
target_model_names_list: List[str],
|
||||
litellm_parent_otel_span: Span,
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
) -> VectorStoreCreateResponse:
|
||||
"""
|
||||
Create a vector store across multiple models.
|
||||
|
||||
Args:
|
||||
create_request: Vector store creation request parameters
|
||||
llm_router: LiteLLM router instance
|
||||
target_model_names_list: List of target model names
|
||||
litellm_parent_otel_span: OpenTelemetry span for tracing
|
||||
user_api_key_dict: User API key authentication details
|
||||
|
||||
Returns:
|
||||
VectorStoreCreateResponse with unified ID
|
||||
"""
|
||||
verbose_logger.info(
|
||||
f"Creating managed vector store for models: {target_model_names_list}"
|
||||
)
|
||||
|
||||
# Create vector store for each model
|
||||
# Convert TypedDict to Dict[str, Any] for base class compatibility
|
||||
request_data_dict: Dict[str, Any] = dict(create_request)
|
||||
responses = await self.create_resource_for_each_model(
|
||||
llm_router=llm_router,
|
||||
request_data=request_data_dict,
|
||||
target_model_names_list=target_model_names_list,
|
||||
litellm_parent_otel_span=litellm_parent_otel_span,
|
||||
)
|
||||
|
||||
# Generate unified ID
|
||||
unified_id = self.generate_unified_resource_id(
|
||||
resource_objects=responses,
|
||||
target_model_names_list=target_model_names_list,
|
||||
)
|
||||
|
||||
# Extract model mappings from responses
|
||||
model_mappings: Dict[str, str] = {}
|
||||
for response in responses:
|
||||
hidden_params = getattr(response, "_hidden_params", {}) or {}
|
||||
model_id = hidden_params.get("model_id")
|
||||
if model_id:
|
||||
# VectorStoreCreateResponse is a TypedDict, use dict access
|
||||
model_mappings[model_id] = response["id"]
|
||||
|
||||
verbose_logger.debug(
|
||||
f"Created vector stores with model mappings: {model_mappings}"
|
||||
)
|
||||
|
||||
# Store in database
|
||||
await self.store_unified_resource_id(
|
||||
unified_resource_id=unified_id,
|
||||
resource_object=responses[0], # Store first response as template
|
||||
litellm_parent_otel_span=litellm_parent_otel_span,
|
||||
model_mappings=model_mappings,
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
)
|
||||
|
||||
# Return response with unified ID
|
||||
# VectorStoreCreateResponse is a TypedDict, so we need to create a new dict with the unified ID
|
||||
response = responses[0].copy()
|
||||
response["id"] = unified_id
|
||||
|
||||
verbose_logger.info(
|
||||
f"Successfully created managed vector store with unified ID: {unified_id}"
|
||||
)
|
||||
|
||||
return response
|
||||
|
||||
async def alist_vector_stores(
|
||||
self,
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
limit: Optional[int] = None,
|
||||
after: Optional[str] = None,
|
||||
order: Optional[str] = None,
|
||||
) -> Dict[str, Any]:
|
||||
"""
|
||||
List vector stores created by a user.
|
||||
|
||||
Args:
|
||||
user_api_key_dict: User API key authentication details
|
||||
limit: Maximum number of vector stores to return
|
||||
after: Cursor for pagination
|
||||
order: Sort order ('asc' or 'desc')
|
||||
|
||||
Returns:
|
||||
Dictionary with list of vector stores and pagination info
|
||||
"""
|
||||
# Use the base class method
|
||||
return await self.list_user_resources(
|
||||
user_api_key_dict=user_api_key_dict,
|
||||
limit=limit,
|
||||
after=after,
|
||||
)
|
||||
|
||||
# ============================================================================
|
||||
# ACCESS CONTROL
|
||||
# ============================================================================
|
||||
|
||||
async def check_vector_store_access(
|
||||
self, vector_store_id: str, user_api_key_dict: UserAPIKeyAuth
|
||||
) -> bool:
|
||||
"""
|
||||
Check if user has access to a vector store.
|
||||
|
||||
Args:
|
||||
vector_store_id: The unified vector store ID
|
||||
user_api_key_dict: User API key authentication details
|
||||
|
||||
Returns:
|
||||
True if user has access, False otherwise
|
||||
"""
|
||||
is_unified_id = is_base64_encoded_unified_id(vector_store_id)
|
||||
|
||||
if is_unified_id:
|
||||
# Check access for managed vector store
|
||||
return await self.can_user_access_unified_resource_id(
|
||||
vector_store_id,
|
||||
user_api_key_dict,
|
||||
)
|
||||
|
||||
# Not a managed vector store, allow access
|
||||
return True
|
||||
|
||||
async def check_managed_vector_store_access(
|
||||
self, data: Dict, user_api_key_dict: UserAPIKeyAuth
|
||||
) -> bool:
|
||||
"""
|
||||
Check if user has access to a managed vector store in request data.
|
||||
|
||||
Args:
|
||||
data: Request data containing vector_store_id
|
||||
user_api_key_dict: User API key authentication details
|
||||
|
||||
Returns:
|
||||
True if this is a managed vector store and user has access
|
||||
|
||||
Raises:
|
||||
HTTPException: If user doesn't have access
|
||||
"""
|
||||
vector_store_id = cast(Optional[str], data.get("vector_store_id"))
|
||||
is_unified_id = (
|
||||
is_base64_encoded_unified_id(vector_store_id)
|
||||
if vector_store_id
|
||||
else False
|
||||
)
|
||||
|
||||
if is_unified_id and vector_store_id:
|
||||
if await self.can_user_access_unified_resource_id(
|
||||
vector_store_id, user_api_key_dict
|
||||
):
|
||||
return True
|
||||
else:
|
||||
raise HTTPException(
|
||||
status_code=403,
|
||||
detail=f"User {user_api_key_dict.user_id} does not have access to vector store {vector_store_id}",
|
||||
)
|
||||
|
||||
return False
|
||||
|
||||
# ============================================================================
|
||||
# PRE-CALL HOOK (For Router Integration)
|
||||
# ============================================================================
|
||||
|
||||
async def async_pre_call_hook(
|
||||
self,
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
cache: Any,
|
||||
data: Dict,
|
||||
call_type: str,
|
||||
) -> Union[Exception, str, Dict, None]:
|
||||
"""
|
||||
Pre-call hook to handle vector store operations.
|
||||
|
||||
This hook intercepts vector store requests and:
|
||||
- Validates access for managed vector stores
|
||||
- Transforms unified IDs to provider-specific IDs
|
||||
- Adds model routing information
|
||||
|
||||
Args:
|
||||
user_api_key_dict: User API key authentication details
|
||||
cache: Cache instance
|
||||
data: Request data
|
||||
call_type: Type of call being made
|
||||
|
||||
Returns:
|
||||
Modified request data or None
|
||||
"""
|
||||
from litellm.llms.base_llm.managed_resources.utils import (
|
||||
is_base64_encoded_unified_id,
|
||||
parse_unified_id,
|
||||
)
|
||||
|
||||
# Handle vector store search operations
|
||||
if call_type == "avector_store_search":
|
||||
vector_store_id = data.get("vector_store_id")
|
||||
|
||||
if vector_store_id:
|
||||
# Check if it's a managed vector store ID
|
||||
decoded_id = is_base64_encoded_unified_id(vector_store_id)
|
||||
|
||||
if decoded_id:
|
||||
verbose_logger.debug(
|
||||
f"Processing managed vector store search: {vector_store_id}"
|
||||
)
|
||||
|
||||
# Check access
|
||||
has_access = await self.can_user_access_unified_resource_id(
|
||||
vector_store_id, user_api_key_dict
|
||||
)
|
||||
|
||||
if not has_access:
|
||||
raise HTTPException(
|
||||
status_code=403,
|
||||
detail=f"User {user_api_key_dict.user_id} does not have access to vector store {vector_store_id}",
|
||||
)
|
||||
|
||||
# Parse the unified ID to extract components
|
||||
parsed_id = parse_unified_id(vector_store_id)
|
||||
|
||||
if parsed_id:
|
||||
# Extract the model ID and provider resource ID
|
||||
model_id = parsed_id.get("model_id")
|
||||
provider_resource_id = parsed_id.get("provider_resource_id")
|
||||
target_model_names = parsed_id.get("target_model_names", [])
|
||||
|
||||
verbose_logger.debug(
|
||||
f"Decoded vector store - model_id: {model_id}, provider_resource_id: {provider_resource_id}, target_model_names: {target_model_names}"
|
||||
)
|
||||
|
||||
# Determine which model to use for routing
|
||||
# Priority: model_id (deployment ID) > first target_model_name
|
||||
routing_model = None
|
||||
if model_id:
|
||||
routing_model = model_id
|
||||
elif target_model_names and len(target_model_names) > 0:
|
||||
routing_model = target_model_names[0]
|
||||
|
||||
# Set the model for routing
|
||||
if routing_model:
|
||||
data["model"] = routing_model
|
||||
verbose_logger.info(
|
||||
f"Routing vector store search to model: {routing_model}"
|
||||
)
|
||||
|
||||
# Replace the unified ID with the provider-specific ID
|
||||
if provider_resource_id:
|
||||
data["vector_store_id"] = provider_resource_id
|
||||
verbose_logger.debug(
|
||||
f"Replaced unified ID with provider resource ID: {provider_resource_id}"
|
||||
)
|
||||
|
||||
# Handle vector store retrieve/delete operations
|
||||
elif call_type in ("avector_store_retrieve", "avector_store_delete"):
|
||||
await self.check_managed_vector_store_access(data, user_api_key_dict)
|
||||
|
||||
# If it's a managed vector store, we'll handle it in the endpoint
|
||||
# No need to transform here as the endpoint will route to the hook
|
||||
|
||||
return data
|
||||
|
||||
# ============================================================================
|
||||
# POST-CALL HOOK (For Response Transformation)
|
||||
# ============================================================================
|
||||
|
||||
async def async_post_call_success_hook(
|
||||
self,
|
||||
data: Dict,
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
response: Any,
|
||||
) -> Any:
|
||||
"""
|
||||
Post-call hook to transform responses.
|
||||
|
||||
This hook can be used to transform responses if needed.
|
||||
For now, it just passes through the response.
|
||||
|
||||
Args:
|
||||
data: Request data
|
||||
user_api_key_dict: User API key authentication details
|
||||
response: Response from the provider
|
||||
|
||||
Returns:
|
||||
Potentially modified response
|
||||
"""
|
||||
# Currently no transformation needed
|
||||
return response
|
||||
|
||||
# ============================================================================
|
||||
# DEPLOYMENT FILTERING
|
||||
# ============================================================================
|
||||
|
||||
async def async_filter_deployments( # type: ignore[override]
|
||||
self,
|
||||
model: str,
|
||||
healthy_deployments: List,
|
||||
messages: Optional[List] = None,
|
||||
request_kwargs: Optional[Dict] = None,
|
||||
parent_otel_span: Optional[Span] = None,
|
||||
) -> List[Dict]:
|
||||
"""
|
||||
Filter deployments based on vector store availability.
|
||||
|
||||
This is used by the router to select only deployments that have
|
||||
the vector store available.
|
||||
|
||||
Note: This method signature is a compromise between CustomLogger and BaseManagedResource
|
||||
parent classes which have incompatible signatures. The type: ignore[override] is necessary
|
||||
due to this multiple inheritance conflict.
|
||||
|
||||
Args:
|
||||
model: Model name
|
||||
healthy_deployments: List of healthy deployments
|
||||
messages: Messages (unused for vector stores, required by CustomLogger interface)
|
||||
request_kwargs: Request kwargs containing vector_store_id and mappings
|
||||
parent_otel_span: OpenTelemetry span for tracing
|
||||
|
||||
Returns:
|
||||
Filtered list of deployments
|
||||
"""
|
||||
return await BaseManagedResource.async_filter_deployments(
|
||||
self,
|
||||
model=model,
|
||||
healthy_deployments=healthy_deployments,
|
||||
request_kwargs=request_kwargs,
|
||||
parent_otel_span=parent_otel_span,
|
||||
resource_id_key="vector_store_id",
|
||||
)
|
||||
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "litellm-enterprise"
|
||||
version = "0.1.31"
|
||||
version = "0.1.32"
|
||||
description = "Package for LiteLLM Enterprise features"
|
||||
authors = ["BerriAI"]
|
||||
readme = "README.md"
|
||||
|
|
@ -22,7 +22,7 @@ requires = ["poetry-core"]
|
|||
build-backend = "poetry.core.masonry.api"
|
||||
|
||||
[tool.commitizen]
|
||||
version = "0.1.31"
|
||||
version = "0.1.32"
|
||||
version_files = [
|
||||
"pyproject.toml:version",
|
||||
"../requirements.txt:litellm-enterprise==",
|
||||
|
|
|
|||
127
litellm-proxy-extras/build_and_publish.md
Normal file
127
litellm-proxy-extras/build_and_publish.md
Normal file
|
|
@ -0,0 +1,127 @@
|
|||
# Build & Publish `litellm-proxy-extras`
|
||||
|
||||
This runbook covers building and publishing a new version of the `litellm-proxy-extras` PyPI package. For use by litellm engineers only.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
- All `schema.prisma` files are in sync (see [migration_runbook.md](./migration_runbook.md) Step 0)
|
||||
- Migration has been generated and committed
|
||||
- You are in the `litellm-proxy-extras/` directory
|
||||
|
||||
## Step 1: Bump the Version
|
||||
|
||||
### Option A: Automatic Version Bump (Recommended)
|
||||
|
||||
Use commitizen to automatically bump the version across all files:
|
||||
|
||||
```bash
|
||||
cd litellm-proxy-extras
|
||||
cz bump --increment patch
|
||||
```
|
||||
|
||||
This will automatically:
|
||||
- Bump the version in `pyproject.toml` (both `[tool.poetry].version` and `[tool.commitizen].version`)
|
||||
- Update the version in `../requirements.txt`
|
||||
- Update the version in `../pyproject.toml` (root)
|
||||
- Create a git commit with the version bump
|
||||
|
||||
Then skip to Step 3 (Install Build Dependencies).
|
||||
|
||||
### Option B: Manual Version Bump
|
||||
|
||||
Update the version in `pyproject.toml`:
|
||||
|
||||
```bash
|
||||
cd litellm-proxy-extras
|
||||
|
||||
# Check current version
|
||||
grep 'version' pyproject.toml
|
||||
```
|
||||
|
||||
Edit `pyproject.toml` and bump the version (both `[tool.poetry].version` and `[tool.commitizen].version`).
|
||||
|
||||
#### Step 2: Update Version in Root Package Files (Manual Only)
|
||||
|
||||
After bumping the version in `litellm-proxy-extras/pyproject.toml`, you **must** also update the version reference in the root-level files:
|
||||
|
||||
| File | Line to update |
|
||||
|------|---------------|
|
||||
| `requirements.txt` | `litellm-proxy-extras==X.Y.Z` |
|
||||
| `pyproject.toml` (root) | `litellm-proxy-extras = {version = "X.Y.Z", optional = true}` |
|
||||
|
||||
```bash
|
||||
# From the repo root — replace OLD with NEW version
|
||||
sed -i '' 's/litellm-proxy-extras==OLD/litellm-proxy-extras==NEW/' requirements.txt
|
||||
sed -i '' 's/litellm-proxy-extras = {version = "OLD"/litellm-proxy-extras = {version = "NEW"/' pyproject.toml
|
||||
```
|
||||
|
||||
> **Do NOT skip this step.** The main `litellm` package pins the extras version — if you don't update these, users will install the old version.
|
||||
|
||||
## Step 3: Install Build Dependencies
|
||||
|
||||
```bash
|
||||
pip install build twine
|
||||
```
|
||||
|
||||
## Step 4: Clean Old Artifacts
|
||||
|
||||
```bash
|
||||
rm -rf dist/ build/ *.egg-info
|
||||
```
|
||||
|
||||
## Step 5: Build the Package
|
||||
|
||||
```bash
|
||||
python3 -m build
|
||||
```
|
||||
|
||||
This creates `.tar.gz` and `.whl` files in the `dist/` directory.
|
||||
|
||||
Verify the build output:
|
||||
|
||||
```bash
|
||||
ls -la dist/
|
||||
```
|
||||
|
||||
## Step 6: Upload to PyPI
|
||||
|
||||
```bash
|
||||
twine upload dist/*
|
||||
```
|
||||
|
||||
You will be prompted for your PyPI API token:
|
||||
|
||||
```
|
||||
Enter your API token: pypi-...
|
||||
```
|
||||
|
||||
> Use `__token__` as the username and your PyPI API token as the password.
|
||||
|
||||
## Quick Reference (Copy-Paste)
|
||||
|
||||
```bash
|
||||
cd litellm-proxy-extras
|
||||
rm -rf dist/ build/ *.egg-info
|
||||
python3 -m build
|
||||
twine upload dist/*
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Do you want to build and publish a new `litellm-proxy-extras` package? (y/n)
|
||||
|
||||
If **yes**, run the following commands in order:
|
||||
|
||||
```bash
|
||||
cd litellm-proxy-extras
|
||||
pip install build twine
|
||||
rm -rf dist/ build/ *.egg-info
|
||||
python3 -m build
|
||||
twine upload dist/*
|
||||
```
|
||||
|
||||
When `twine upload` runs, enter your PyPI credentials:
|
||||
- **Username:** `__token__`
|
||||
- **Password:** *(paste your PyPI API key)*
|
||||
|
||||
If **no**, you're done — no package publish needed.
|
||||
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.35-py3-none-any.whl
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.35-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.35.tar.gz
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.35.tar.gz
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.36-py3-none-any.whl
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.36-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.36.tar.gz
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.36.tar.gz
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.37-py3-none-any.whl
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.37-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.37.tar.gz
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.37.tar.gz
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.40-py3-none-any.whl
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.40-py3-none-any.whl
vendored
Normal file
Binary file not shown.
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.40.tar.gz
vendored
Normal file
BIN
litellm-proxy-extras/dist/litellm_proxy_extras-0.4.40.tar.gz
vendored
Normal file
Binary file not shown.
|
|
@ -0,0 +1,19 @@
|
|||
-- CreateTable
|
||||
CREATE TABLE "LiteLLM_DeprecatedVerificationToken" (
|
||||
"id" TEXT NOT NULL,
|
||||
"token" TEXT NOT NULL,
|
||||
"active_token_id" TEXT NOT NULL,
|
||||
"revoke_at" TIMESTAMP(3) NOT NULL,
|
||||
"created_at" TIMESTAMP(3) NOT NULL DEFAULT CURRENT_TIMESTAMP,
|
||||
|
||||
CONSTRAINT "LiteLLM_DeprecatedVerificationToken_pkey" PRIMARY KEY ("id")
|
||||
);
|
||||
|
||||
-- CreateIndex
|
||||
CREATE UNIQUE INDEX "LiteLLM_DeprecatedVerificationToken_token_key" ON "LiteLLM_DeprecatedVerificationToken"("token");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeprecatedVerificationToken_token_revoke_at_idx" ON "LiteLLM_DeprecatedVerificationToken"("token", "revoke_at");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_DeprecatedVerificationToken_revoke_at_idx" ON "LiteLLM_DeprecatedVerificationToken"("revoke_at");
|
||||
|
|
@ -0,0 +1,3 @@
|
|||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_PolicyAttachmentTable" ADD COLUMN "tags" TEXT[] DEFAULT ARRAY[]::TEXT[];
|
||||
|
||||
|
|
@ -0,0 +1,33 @@
|
|||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_DeletedTeamTable" ADD COLUMN "access_group_ids" TEXT[] DEFAULT ARRAY[]::TEXT[];
|
||||
|
||||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_DeletedVerificationToken" ADD COLUMN "access_group_ids" TEXT[] DEFAULT ARRAY[]::TEXT[];
|
||||
|
||||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_TeamTable" ADD COLUMN "access_group_ids" TEXT[] DEFAULT ARRAY[]::TEXT[];
|
||||
|
||||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_VerificationToken" ADD COLUMN "access_group_ids" TEXT[] DEFAULT ARRAY[]::TEXT[];
|
||||
|
||||
-- CreateTable
|
||||
CREATE TABLE "LiteLLM_AccessGroupTable" (
|
||||
"access_group_id" TEXT NOT NULL,
|
||||
"access_group_name" TEXT NOT NULL,
|
||||
"description" TEXT,
|
||||
"access_model_ids" TEXT[] DEFAULT ARRAY[]::TEXT[],
|
||||
"access_mcp_server_ids" TEXT[] DEFAULT ARRAY[]::TEXT[],
|
||||
"access_agent_ids" TEXT[] DEFAULT ARRAY[]::TEXT[],
|
||||
"assigned_team_ids" TEXT[] DEFAULT ARRAY[]::TEXT[],
|
||||
"assigned_key_ids" TEXT[] DEFAULT ARRAY[]::TEXT[],
|
||||
"created_at" TIMESTAMP(3) NOT NULL DEFAULT CURRENT_TIMESTAMP,
|
||||
"created_by" TEXT,
|
||||
"updated_at" TIMESTAMP(3) NOT NULL DEFAULT CURRENT_TIMESTAMP,
|
||||
"updated_by" TEXT,
|
||||
|
||||
CONSTRAINT "LiteLLM_AccessGroupTable_pkey" PRIMARY KEY ("access_group_id")
|
||||
);
|
||||
|
||||
-- CreateIndex
|
||||
CREATE UNIQUE INDEX "LiteLLM_AccessGroupTable_access_group_name_key" ON "LiteLLM_AccessGroupTable"("access_group_name");
|
||||
|
||||
|
|
@ -0,0 +1,22 @@
|
|||
-- CreateTable
|
||||
CREATE TABLE "LiteLLM_ManagedVectorStoreTable" (
|
||||
"id" TEXT NOT NULL,
|
||||
"unified_resource_id" TEXT NOT NULL,
|
||||
"resource_object" JSONB,
|
||||
"model_mappings" JSONB NOT NULL,
|
||||
"flat_model_resource_ids" TEXT[] DEFAULT ARRAY[]::TEXT[],
|
||||
"storage_backend" TEXT,
|
||||
"storage_url" TEXT,
|
||||
"created_at" TIMESTAMP(3) NOT NULL DEFAULT CURRENT_TIMESTAMP,
|
||||
"created_by" TEXT,
|
||||
"updated_at" TIMESTAMP(3) NOT NULL,
|
||||
"updated_by" TEXT,
|
||||
|
||||
CONSTRAINT "LiteLLM_ManagedVectorStoreTable_pkey" PRIMARY KEY ("id")
|
||||
);
|
||||
|
||||
-- CreateIndex
|
||||
CREATE UNIQUE INDEX "LiteLLM_ManagedVectorStoreTable_unified_resource_id_key" ON "LiteLLM_ManagedVectorStoreTable"("unified_resource_id");
|
||||
|
||||
-- CreateIndex
|
||||
CREATE INDEX "LiteLLM_ManagedVectorStoreTable_unified_resource_id_idx" ON "LiteLLM_ManagedVectorStoreTable"("unified_resource_id");
|
||||
|
|
@ -0,0 +1,3 @@
|
|||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_AccessGroupTable" DROP COLUMN "access_model_ids",
|
||||
ADD COLUMN "access_model_names" TEXT[] DEFAULT ARRAY[]::TEXT[];
|
||||
|
|
@ -0,0 +1,3 @@
|
|||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_GuardrailsTable" ADD COLUMN "team_id" TEXT;
|
||||
|
||||
|
|
@ -0,0 +1,2 @@
|
|||
-- This is an empty migration.
|
||||
|
||||
|
|
@ -0,0 +1,3 @@
|
|||
-- AlterTable
|
||||
ALTER TABLE "LiteLLM_PolicyTable" ADD COLUMN "pipeline" JSONB;
|
||||
|
||||
|
|
@ -128,6 +128,7 @@ model LiteLLM_TeamTable {
|
|||
model_max_budget Json @default("{}")
|
||||
router_settings Json? @default("{}")
|
||||
team_member_permissions String[] @default([])
|
||||
access_group_ids String[] @default([])
|
||||
policies String[] @default([])
|
||||
model_id Int? @unique // id for LiteLLM_ModelTable -> stores team-level model aliases
|
||||
allow_team_guardrail_config Boolean @default(false) // if true, team admin can configure guardrails for this team
|
||||
|
|
@ -161,6 +162,7 @@ model LiteLLM_DeletedTeamTable {
|
|||
model_max_budget Json @default("{}")
|
||||
router_settings Json? @default("{}")
|
||||
team_member_permissions String[] @default([])
|
||||
access_group_ids String[] @default([])
|
||||
policies String[] @default([])
|
||||
model_id Int? // id for LiteLLM_ModelTable -> stores team-level model aliases
|
||||
allow_team_guardrail_config Boolean @default(false)
|
||||
|
|
@ -293,6 +295,7 @@ model LiteLLM_VerificationToken {
|
|||
allowed_cache_controls String[] @default([])
|
||||
allowed_routes String[] @default([])
|
||||
policies String[] @default([])
|
||||
access_group_ids String[] @default([])
|
||||
model_spend Json @default("{}")
|
||||
model_max_budget Json @default("{}")
|
||||
budget_id String?
|
||||
|
|
@ -322,6 +325,19 @@ model LiteLLM_VerificationToken {
|
|||
@@index([budget_reset_at, expires])
|
||||
}
|
||||
|
||||
// Deprecated keys during grace period - allows old key to work until revoke_at
|
||||
model LiteLLM_DeprecatedVerificationToken {
|
||||
id String @id @default(uuid())
|
||||
token String // Hashed old key
|
||||
active_token_id String // Current token hash in LiteLLM_VerificationToken
|
||||
revoke_at DateTime // When the old key stops working
|
||||
created_at DateTime @default(now()) @map("created_at")
|
||||
|
||||
@@unique([token])
|
||||
@@index([token, revoke_at])
|
||||
@@index([revoke_at])
|
||||
}
|
||||
|
||||
// Audit table for deleted keys - preserves spend and key information for historical tracking
|
||||
model LiteLLM_DeletedVerificationToken {
|
||||
id String @id @default(uuid())
|
||||
|
|
@ -348,6 +364,7 @@ model LiteLLM_DeletedVerificationToken {
|
|||
allowed_cache_controls String[] @default([])
|
||||
allowed_routes String[] @default([])
|
||||
policies String[] @default([])
|
||||
access_group_ids String[] @default([])
|
||||
model_spend Json @default("{}")
|
||||
model_max_budget Json @default("{}")
|
||||
router_settings Json? @default("{}")
|
||||
|
|
@ -766,6 +783,22 @@ model LiteLLM_ManagedObjectTable { // for batches or finetuning jobs which use t
|
|||
@@index([model_object_id])
|
||||
}
|
||||
|
||||
model LiteLLM_ManagedVectorStoreTable {
|
||||
id String @id @default(uuid())
|
||||
unified_resource_id String @unique // The base64 encoded unified vector store ID
|
||||
resource_object Json? // Stores the VectorStoreCreateResponse
|
||||
model_mappings Json // Maps model_id -> provider_vector_store_id
|
||||
flat_model_resource_ids String[] @default([]) // Flat list of provider vector store IDs for faster querying
|
||||
storage_backend String? // Storage backend name (if applicable)
|
||||
storage_url String? // Storage URL (if applicable)
|
||||
created_at DateTime @default(now())
|
||||
created_by String?
|
||||
updated_at DateTime @updatedAt
|
||||
updated_by String?
|
||||
|
||||
@@index([unified_resource_id])
|
||||
}
|
||||
|
||||
model LiteLLM_ManagedVectorStoresTable {
|
||||
vector_store_id String @id
|
||||
custom_llm_provider String
|
||||
|
|
@ -900,6 +933,7 @@ model LiteLLM_PolicyTable {
|
|||
guardrails_add String[] @default([])
|
||||
guardrails_remove String[] @default([])
|
||||
condition Json? @default("{}") // Policy conditions (e.g., model matching)
|
||||
pipeline Json? // Optional guardrail pipeline (mode + steps[])
|
||||
created_at DateTime @default(now())
|
||||
created_by String?
|
||||
updated_at DateTime @default(now()) @updatedAt
|
||||
|
|
@ -914,8 +948,29 @@ model LiteLLM_PolicyAttachmentTable {
|
|||
teams String[] @default([]) // Team aliases or patterns
|
||||
keys String[] @default([]) // Key aliases or patterns
|
||||
models String[] @default([]) // Model names or patterns
|
||||
tags String[] @default([]) // Tag patterns (e.g., ["healthcare", "prod-*"])
|
||||
created_at DateTime @default(now())
|
||||
created_by String?
|
||||
updated_at DateTime @default(now()) @updatedAt
|
||||
updated_by String?
|
||||
}
|
||||
|
||||
//Unified Access Groups table for storing unified access groups
|
||||
model LiteLLM_AccessGroupTable {
|
||||
access_group_id String @id @default(uuid())
|
||||
access_group_name String @unique
|
||||
description String?
|
||||
|
||||
// Resource memberships - explicit arrays per type
|
||||
access_model_names String[] @default([])
|
||||
access_mcp_server_ids String[] @default([])
|
||||
access_agent_ids String[] @default([])
|
||||
|
||||
assigned_team_ids String[] @default([])
|
||||
assigned_key_ids String[] @default([])
|
||||
|
||||
created_at DateTime @default(now())
|
||||
created_by String?
|
||||
updated_at DateTime @default(now()) @updatedAt
|
||||
updated_by String?
|
||||
}
|
||||
|
|
@ -2,7 +2,35 @@
|
|||
|
||||
This is a runbook for creating and running database migrations for the LiteLLM proxy. For use for litellm engineers only.
|
||||
|
||||
## Quick Start
|
||||
## Step 0: Sync All `schema.prisma` Files
|
||||
|
||||
Before doing anything else, make sure all `schema.prisma` files in the repo are in sync. There are multiple copies that must match:
|
||||
|
||||
| File | Purpose |
|
||||
|------|---------|
|
||||
| `schema.prisma` (repo root) | Source of truth |
|
||||
| `litellm/proxy/schema.prisma` | Used by the proxy server |
|
||||
| `litellm-proxy-extras/litellm_proxy_extras/schema.prisma` | Used for migration generation |
|
||||
|
||||
**Sync process:**
|
||||
|
||||
```bash
|
||||
# 1. Diff all schema files against the root source of truth
|
||||
diff schema.prisma litellm/proxy/schema.prisma
|
||||
diff schema.prisma litellm-proxy-extras/litellm_proxy_extras/schema.prisma
|
||||
|
||||
# 2. If there are differences, copy the root schema to all locations
|
||||
cp schema.prisma litellm/proxy/schema.prisma
|
||||
cp schema.prisma litellm-proxy-extras/litellm_proxy_extras/schema.prisma
|
||||
|
||||
# 3. Verify all files are now identical
|
||||
diff schema.prisma litellm/proxy/schema.prisma && echo "proxy schema in sync" || echo "MISMATCH"
|
||||
diff schema.prisma litellm-proxy-extras/litellm_proxy_extras/schema.prisma && echo "extras schema in sync" || echo "MISMATCH"
|
||||
```
|
||||
|
||||
> **Do NOT proceed to migration generation until all schema files are identical.**
|
||||
|
||||
## Step 1: Quick Start — Generate Migration
|
||||
|
||||
```bash
|
||||
# Install deps (one time)
|
||||
|
|
@ -43,8 +71,13 @@ rm -rf litellm-proxy-extras/litellm_proxy_extras/migrations/[empty_dir]
|
|||
|
||||
## Rules
|
||||
|
||||
- Update `schema.prisma` first
|
||||
- Sync all `schema.prisma` files first (Step 0)
|
||||
- Update `schema.prisma` at the repo root first, then sync copies
|
||||
- Review generated SQL before committing
|
||||
- Use descriptive migration names
|
||||
- Never edit existing migration files
|
||||
- Commit schema + migration together
|
||||
|
||||
---
|
||||
|
||||
**Done with migration?** See [build_and_publish.md](./build_and_publish.md) to publish a new `litellm-proxy-extras` package.
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "litellm-proxy-extras"
|
||||
version = "0.4.34"
|
||||
version = "0.4.40"
|
||||
description = "Additional files for the LiteLLM Proxy. Reduces the size of the main litellm package."
|
||||
authors = ["BerriAI"]
|
||||
readme = "README.md"
|
||||
|
|
@ -22,7 +22,7 @@ requires = ["poetry-core"]
|
|||
build-backend = "poetry.core.masonry.api"
|
||||
|
||||
[tool.commitizen]
|
||||
version = "0.4.34"
|
||||
version = "0.4.40"
|
||||
version_files = [
|
||||
"pyproject.toml:version",
|
||||
"../requirements.txt:litellm-proxy-extras==",
|
||||
|
|
|
|||
|
|
@ -175,6 +175,7 @@ _async_failure_callback: List[Union[str, Callable, "CustomLogger"]] = ( # Custo
|
|||
pre_call_rules: List[Callable] = []
|
||||
post_call_rules: List[Callable] = []
|
||||
turn_off_message_logging: Optional[bool] = False
|
||||
standard_logging_payload_excluded_fields: Optional[List[str]] = None # Fields to exclude from StandardLoggingPayload before callbacks receive it
|
||||
log_raw_request_response: bool = False
|
||||
redact_messages_in_exceptions: Optional[bool] = False
|
||||
redact_user_api_key_info: Optional[bool] = False
|
||||
|
|
@ -337,6 +338,10 @@ model_cost_map_url: str = os.getenv(
|
|||
"LITELLM_MODEL_COST_MAP_URL",
|
||||
"https://raw.githubusercontent.com/BerriAI/litellm/main/model_prices_and_context_window.json",
|
||||
)
|
||||
anthropic_beta_headers_url: str = os.getenv(
|
||||
"LITELLM_ANTHROPIC_BETA_HEADERS_URL",
|
||||
"https://raw.githubusercontent.com/BerriAI/litellm/main/litellm/anthropic_beta_headers_config.json",
|
||||
)
|
||||
suppress_debug_info = False
|
||||
dynamodb_table_name: Optional[str] = None
|
||||
s3_callback_params: Optional[Dict] = None
|
||||
|
|
@ -1155,6 +1160,7 @@ from .exceptions import (
|
|||
BadRequestError,
|
||||
ImageFetchError,
|
||||
NotFoundError,
|
||||
PermissionDeniedError,
|
||||
RateLimitError,
|
||||
ServiceUnavailableError,
|
||||
BadGatewayError,
|
||||
|
|
|
|||
|
|
@ -275,7 +275,6 @@ LLM_CONFIG_NAMES = (
|
|||
"LmStudioEmbeddingConfig",
|
||||
"NscaleConfig",
|
||||
"PerplexityChatConfig",
|
||||
"PerplexityResponsesConfig",
|
||||
"AzureOpenAIO1Config",
|
||||
"IBMWatsonXAIConfig",
|
||||
"IBMWatsonXChatConfig",
|
||||
|
|
|
|||
|
|
@ -312,10 +312,12 @@ class ServiceLogging(CustomLogger):
|
|||
_duration, type(_duration)
|
||||
)
|
||||
) # invalid _duration value
|
||||
# Batch polling callbacks (check_batch_cost) don't include call_type in kwargs.
|
||||
# Use .get() to avoid KeyError.
|
||||
await self.async_service_success_hook(
|
||||
service=ServiceTypes.LITELLM,
|
||||
duration=_duration,
|
||||
call_type=kwargs["call_type"],
|
||||
call_type=kwargs.get("call_type", "unknown")
|
||||
)
|
||||
except Exception as e:
|
||||
raise e
|
||||
|
|
|
|||
|
|
@ -1,33 +1,152 @@
|
|||
{
|
||||
"description": "Unsupported Anthropic beta headers for each provider. Headers listed here will be dropped. Headers not listed are passed through as-is.",
|
||||
"anthropic": [],
|
||||
"azure_ai": [],
|
||||
"bedrock_converse": [
|
||||
"prompt-caching-scope-2026-01-05",
|
||||
"bash_20250124",
|
||||
"bash_20241022",
|
||||
"text_editor_20250124",
|
||||
"text_editor_20241022",
|
||||
"compact-2026-01-12",
|
||||
"advanced-tool-use-2025-11-20",
|
||||
"web-fetch-2025-09-10",
|
||||
"code-execution-2025-08-25",
|
||||
"skills-2025-10-02",
|
||||
"files-api-2025-04-14",
|
||||
"fast-mode-2026-02-01"
|
||||
],
|
||||
"bedrock": [
|
||||
"advanced-tool-use-2025-11-20",
|
||||
"prompt-caching-scope-2026-01-05",
|
||||
"structured-outputs-2025-11-13",
|
||||
"web-fetch-2025-09-10",
|
||||
"code-execution-2025-08-25",
|
||||
"skills-2025-10-02",
|
||||
"files-api-2025-04-14",
|
||||
"fast-mode-2026-02-01",
|
||||
"mcp-servers-2025-12-04"
|
||||
],
|
||||
"vertex_ai": [
|
||||
"prompt-caching-scope-2026-01-05"
|
||||
]
|
||||
}
|
||||
"description": "Mapping of Anthropic beta headers for each provider. Keys are input header names, values are provider-specific header names (or null if unsupported). Only headers present in mapping keys with non-null values can be forwarded.",
|
||||
"anthropic": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"bash_20241022": null,
|
||||
"bash_20250124": null,
|
||||
"code-execution-2025-08-25": "code-execution-2025-08-25",
|
||||
"compact-2026-01-12": "compact-2026-01-12",
|
||||
"computer-use-2025-01-24": "computer-use-2025-01-24",
|
||||
"computer-use-2025-11-24": "computer-use-2025-11-24",
|
||||
"context-1m-2025-08-07": "context-1m-2025-08-07",
|
||||
"context-management-2025-06-27": "context-management-2025-06-27",
|
||||
"effort-2025-11-24": "effort-2025-11-24",
|
||||
"fast-mode-2026-02-01": "fast-mode-2026-02-01",
|
||||
"files-api-2025-04-14": "files-api-2025-04-14",
|
||||
"structured-output-2024-03-01": null,
|
||||
"fine-grained-tool-streaming-2025-05-14": "fine-grained-tool-streaming-2025-05-14",
|
||||
"interleaved-thinking-2025-05-14": "interleaved-thinking-2025-05-14",
|
||||
"mcp-client-2025-11-20": "mcp-client-2025-11-20",
|
||||
"mcp-client-2025-04-04": "mcp-client-2025-04-04",
|
||||
"mcp-servers-2025-12-04": null,
|
||||
"oauth-2025-04-20": "oauth-2025-04-20",
|
||||
"output-128k-2025-02-19": "output-128k-2025-02-19",
|
||||
"prompt-caching-scope-2026-01-05": "prompt-caching-scope-2026-01-05",
|
||||
"skills-2025-10-02": "skills-2025-10-02",
|
||||
"structured-outputs-2025-11-13": "structured-outputs-2025-11-13",
|
||||
"text_editor_20241022": null,
|
||||
"text_editor_20250124": null,
|
||||
"token-efficient-tools-2025-02-19": "token-efficient-tools-2025-02-19",
|
||||
"web-fetch-2025-09-10": "web-fetch-2025-09-10",
|
||||
"web-search-2025-03-05": "web-search-2025-03-05"
|
||||
},
|
||||
"azure_ai": {
|
||||
"advanced-tool-use-2025-11-20": "advanced-tool-use-2025-11-20",
|
||||
"bash_20241022": null,
|
||||
"bash_20250124": null,
|
||||
"code-execution-2025-08-25": "code-execution-2025-08-25",
|
||||
"compact-2026-01-12": null,
|
||||
"computer-use-2025-01-24": "computer-use-2025-01-24",
|
||||
"computer-use-2025-11-24": "computer-use-2025-11-24",
|
||||
"context-1m-2025-08-07": "context-1m-2025-08-07",
|
||||
"context-management-2025-06-27": "context-management-2025-06-27",
|
||||
"effort-2025-11-24": "effort-2025-11-24",
|
||||
"fast-mode-2026-02-01": null,
|
||||
"files-api-2025-04-14": "files-api-2025-04-14",
|
||||
"fine-grained-tool-streaming-2025-05-14": null,
|
||||
"interleaved-thinking-2025-05-14": "interleaved-thinking-2025-05-14",
|
||||
"mcp-client-2025-11-20": "mcp-client-2025-11-20",
|
||||
"mcp-client-2025-04-04": "mcp-client-2025-04-04",
|
||||
"mcp-servers-2025-12-04": null,
|
||||
"output-128k-2025-02-19": null,
|
||||
"structured-output-2024-03-01": null,
|
||||
"prompt-caching-scope-2026-01-05": "prompt-caching-scope-2026-01-05",
|
||||
"skills-2025-10-02": "skills-2025-10-02",
|
||||
"structured-outputs-2025-11-13": "structured-outputs-2025-11-13",
|
||||
"text_editor_20241022": null,
|
||||
"text_editor_20250124": null,
|
||||
"token-efficient-tools-2025-02-19": null,
|
||||
"web-fetch-2025-09-10": "web-fetch-2025-09-10",
|
||||
"web-search-2025-03-05": "web-search-2025-03-05"
|
||||
},
|
||||
"bedrock_converse": {
|
||||
"advanced-tool-use-2025-11-20": null,
|
||||
"bash_20241022": null,
|
||||
"bash_20250124": null,
|
||||
"code-execution-2025-08-25": null,
|
||||
"compact-2026-01-12": null,
|
||||
"computer-use-2025-01-24": "computer-use-2025-01-24",
|
||||
"computer-use-2025-11-24": "computer-use-2025-11-24",
|
||||
"context-1m-2025-08-07": null,
|
||||
"context-management-2025-06-27": "context-management-2025-06-27",
|
||||
"effort-2025-11-24": null,
|
||||
"fast-mode-2026-02-01": null,
|
||||
"files-api-2025-04-14": null,
|
||||
"fine-grained-tool-streaming-2025-05-14": null,
|
||||
"interleaved-thinking-2025-05-14": "interleaved-thinking-2025-05-14",
|
||||
"mcp-client-2025-11-20": null,
|
||||
"mcp-client-2025-04-04": null,
|
||||
"mcp-servers-2025-12-04": null,
|
||||
"output-128k-2025-02-19": null,
|
||||
"structured-output-2024-03-01": null,
|
||||
"prompt-caching-scope-2026-01-05": null,
|
||||
"skills-2025-10-02": null,
|
||||
"structured-outputs-2025-11-13": "structured-outputs-2025-11-13",
|
||||
"text_editor_20241022": null,
|
||||
"text_editor_20250124": null,
|
||||
"token-efficient-tools-2025-02-19": null,
|
||||
"tool-search-tool-2025-10-19": null,
|
||||
"web-fetch-2025-09-10": null,
|
||||
"web-search-2025-03-05": null
|
||||
},
|
||||
"bedrock": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"bash_20241022": null,
|
||||
"bash_20250124": null,
|
||||
"code-execution-2025-08-25": null,
|
||||
"compact-2026-01-12": "compact-2026-01-12",
|
||||
"computer-use-2025-01-24": "computer-use-2025-01-24",
|
||||
"computer-use-2025-11-24": "computer-use-2025-11-24",
|
||||
"context-1m-2025-08-07": "context-1m-2025-08-07",
|
||||
"context-management-2025-06-27": "context-management-2025-06-27",
|
||||
"effort-2025-11-24": null,
|
||||
"fast-mode-2026-02-01": null,
|
||||
"files-api-2025-04-14": null,
|
||||
"fine-grained-tool-streaming-2025-05-14": null,
|
||||
"interleaved-thinking-2025-05-14": "interleaved-thinking-2025-05-14",
|
||||
"mcp-client-2025-11-20": null,
|
||||
"mcp-client-2025-04-04": null,
|
||||
"mcp-servers-2025-12-04": null,
|
||||
"output-128k-2025-02-19": null,
|
||||
"structured-output-2024-03-01": null,
|
||||
"prompt-caching-scope-2026-01-05": null,
|
||||
"skills-2025-10-02": null,
|
||||
"structured-outputs-2025-11-13": null,
|
||||
"text_editor_20241022": null,
|
||||
"text_editor_20250124": null,
|
||||
"token-efficient-tools-2025-02-19": null,
|
||||
"tool-search-tool-2025-10-19": "tool-search-tool-2025-10-19",
|
||||
"web-fetch-2025-09-10": null,
|
||||
"web-search-2025-03-05": null
|
||||
},
|
||||
"vertex_ai": {
|
||||
"advanced-tool-use-2025-11-20": "tool-search-tool-2025-10-19",
|
||||
"bash_20241022": null,
|
||||
"bash_20250124": null,
|
||||
"code-execution-2025-08-25": null,
|
||||
"compact-2026-01-12": null,
|
||||
"computer-use-2025-01-24": "computer-use-2025-01-24",
|
||||
"computer-use-2025-11-24": "computer-use-2025-11-24",
|
||||
"context-1m-2025-08-07": null,
|
||||
"context-management-2025-06-27": "context-management-2025-06-27",
|
||||
"effort-2025-11-24": null,
|
||||
"fast-mode-2026-02-01": null,
|
||||
"files-api-2025-04-14": null,
|
||||
"fine-grained-tool-streaming-2025-05-14": null,
|
||||
"interleaved-thinking-2025-05-14": "interleaved-thinking-2025-05-14",
|
||||
"mcp-client-2025-11-20": null,
|
||||
"mcp-client-2025-04-04": null,
|
||||
"mcp-servers-2025-12-04": null,
|
||||
"output-128k-2025-02-19": null,
|
||||
"structured-output-2024-03-01": null,
|
||||
"prompt-caching-scope-2026-01-05": null,
|
||||
"skills-2025-10-02": null,
|
||||
"structured-outputs-2025-11-13": null,
|
||||
"text_editor_20241022": null,
|
||||
"text_editor_20250124": null,
|
||||
"token-efficient-tools-2025-02-19": null,
|
||||
"tool-search-tool-2025-10-19": "tool-search-tool-2025-10-19",
|
||||
"web-fetch-2025-09-10": null,
|
||||
"web-search-2025-03-05": "web-search-2025-03-05"
|
||||
}
|
||||
}
|
||||
|
|
@ -2,30 +2,170 @@
|
|||
Centralized manager for Anthropic beta headers across different providers.
|
||||
|
||||
This module provides utilities to:
|
||||
1. Load beta header configuration from JSON (lists unsupported headers per provider)
|
||||
2. Filter out unsupported beta headers
|
||||
1. Load beta header configuration from JSON (mapping of supported headers per provider)
|
||||
2. Filter and map beta headers based on provider support
|
||||
3. Handle provider-specific header name mappings (e.g., advanced-tool-use -> tool-search-tool)
|
||||
4. Support remote fetching and caching similar to model cost map
|
||||
|
||||
Design:
|
||||
- JSON config lists UNSUPPORTED headers for each provider
|
||||
- Headers not in the unsupported list are passed through
|
||||
- Header mappings allow renaming headers for specific providers
|
||||
- JSON config contains mapping of beta headers for each provider
|
||||
- Keys are input header names, values are provider-specific header names (or null if unsupported)
|
||||
- Only headers present in mapping keys with non-null values can be forwarded
|
||||
- This enforces stricter validation than the previous unsupported list approach
|
||||
|
||||
Configuration can be loaded from:
|
||||
- Remote URL (default): Fetches from GitHub repository
|
||||
- Local file: Set LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS=True to use bundled config only
|
||||
|
||||
Environment Variables:
|
||||
- LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS: Set to "True" to disable remote fetching
|
||||
- LITELLM_ANTHROPIC_BETA_HEADERS_URL: Custom URL for remote config (optional)
|
||||
"""
|
||||
|
||||
import json
|
||||
import os
|
||||
from importlib.resources import files
|
||||
from typing import Dict, List, Optional, Set
|
||||
|
||||
import httpx
|
||||
|
||||
from litellm.litellm_core_utils.litellm_logging import verbose_logger
|
||||
|
||||
# Cache for the loaded configuration
|
||||
_BETA_HEADERS_CONFIG: Optional[Dict] = None
|
||||
|
||||
|
||||
class GetAnthropicBetaHeadersConfig:
|
||||
"""
|
||||
Handles fetching, validating, and loading the Anthropic beta headers configuration.
|
||||
|
||||
Similar to GetModelCostMap, this class manages the lifecycle of the beta headers
|
||||
configuration with support for remote fetching and local fallback.
|
||||
"""
|
||||
|
||||
@staticmethod
|
||||
def load_local_beta_headers_config() -> Dict:
|
||||
"""Load the local backup beta headers config bundled with the package."""
|
||||
try:
|
||||
content = json.loads(
|
||||
files("litellm")
|
||||
.joinpath("anthropic_beta_headers_config.json")
|
||||
.read_text(encoding="utf-8")
|
||||
)
|
||||
return content
|
||||
except Exception as e:
|
||||
verbose_logger.error(f"Failed to load local beta headers config: {e}")
|
||||
# Return empty config as fallback
|
||||
return {
|
||||
"anthropic": {},
|
||||
"azure_ai": {},
|
||||
"bedrock": {},
|
||||
"bedrock_converse": {},
|
||||
"vertex_ai": {},
|
||||
"provider_aliases": {}
|
||||
}
|
||||
|
||||
@staticmethod
|
||||
def _check_is_valid_dict(fetched_config: dict) -> bool:
|
||||
"""Check if fetched config is a non-empty dict with expected structure."""
|
||||
if not isinstance(fetched_config, dict):
|
||||
verbose_logger.warning(
|
||||
"LiteLLM: Fetched beta headers config is not a dict (type=%s). "
|
||||
"Falling back to local backup.",
|
||||
type(fetched_config).__name__,
|
||||
)
|
||||
return False
|
||||
|
||||
if len(fetched_config) == 0:
|
||||
verbose_logger.warning(
|
||||
"LiteLLM: Fetched beta headers config is empty. "
|
||||
"Falling back to local backup.",
|
||||
)
|
||||
return False
|
||||
|
||||
# Check for at least one provider key
|
||||
provider_keys = ["anthropic", "azure_ai", "bedrock", "bedrock_converse", "vertex_ai"]
|
||||
has_provider = any(key in fetched_config for key in provider_keys)
|
||||
|
||||
if not has_provider:
|
||||
verbose_logger.warning(
|
||||
"LiteLLM: Fetched beta headers config missing provider keys. "
|
||||
"Falling back to local backup.",
|
||||
)
|
||||
return False
|
||||
|
||||
return True
|
||||
|
||||
@classmethod
|
||||
def validate_beta_headers_config(cls, fetched_config: dict) -> bool:
|
||||
"""
|
||||
Validate the integrity of a fetched beta headers config.
|
||||
|
||||
Returns True if all checks pass, False otherwise.
|
||||
"""
|
||||
return cls._check_is_valid_dict(fetched_config)
|
||||
|
||||
@staticmethod
|
||||
def fetch_remote_beta_headers_config(url: str, timeout: int = 5) -> dict:
|
||||
"""
|
||||
Fetch the beta headers config from a remote URL.
|
||||
|
||||
Returns the parsed JSON dict. Raises on network/parse errors
|
||||
(caller is expected to handle).
|
||||
"""
|
||||
response = httpx.get(url, timeout=timeout)
|
||||
response.raise_for_status()
|
||||
return response.json()
|
||||
|
||||
|
||||
def get_beta_headers_config(url: str) -> dict:
|
||||
"""
|
||||
Public entry point — returns the beta headers config dict.
|
||||
|
||||
1. If ``LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS`` is set, uses the local backup only.
|
||||
2. Otherwise fetches from ``url``, validates integrity, and falls back
|
||||
to the local backup on any failure.
|
||||
|
||||
Args:
|
||||
url: URL to fetch the remote beta headers configuration from
|
||||
|
||||
Returns:
|
||||
Dict containing the beta headers configuration
|
||||
"""
|
||||
# Check if local-only mode is enabled
|
||||
if os.getenv("LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS", "").lower() == "true":
|
||||
# verbose_logger.debug("Using local Anthropic beta headers config (LITELLM_LOCAL_ANTHROPIC_BETA_HEADERS=True)")
|
||||
return GetAnthropicBetaHeadersConfig.load_local_beta_headers_config()
|
||||
|
||||
try:
|
||||
content = GetAnthropicBetaHeadersConfig.fetch_remote_beta_headers_config(url)
|
||||
except Exception as e:
|
||||
verbose_logger.warning(
|
||||
"LiteLLM: Failed to fetch remote beta headers config from %s: %s. "
|
||||
"Falling back to local backup.",
|
||||
url,
|
||||
str(e),
|
||||
)
|
||||
return GetAnthropicBetaHeadersConfig.load_local_beta_headers_config()
|
||||
|
||||
# Validate the fetched config
|
||||
if not GetAnthropicBetaHeadersConfig.validate_beta_headers_config(fetched_config=content):
|
||||
verbose_logger.warning(
|
||||
"LiteLLM: Fetched beta headers config failed integrity check. "
|
||||
"Using local backup instead. url=%s",
|
||||
url,
|
||||
)
|
||||
return GetAnthropicBetaHeadersConfig.load_local_beta_headers_config()
|
||||
|
||||
return content
|
||||
|
||||
|
||||
def _load_beta_headers_config() -> Dict:
|
||||
"""
|
||||
Load the beta headers configuration from JSON file.
|
||||
Uses caching to avoid repeated file reads.
|
||||
Load the beta headers configuration.
|
||||
Uses caching to avoid repeated fetches/file reads.
|
||||
|
||||
This function is called by all public API functions and manages the global cache.
|
||||
|
||||
Returns:
|
||||
Dict containing the beta headers configuration
|
||||
|
|
@ -35,26 +175,27 @@ def _load_beta_headers_config() -> Dict:
|
|||
if _BETA_HEADERS_CONFIG is not None:
|
||||
return _BETA_HEADERS_CONFIG
|
||||
|
||||
config_path = os.path.join(
|
||||
os.path.dirname(__file__),
|
||||
"anthropic_beta_headers_config.json"
|
||||
)
|
||||
# Get the URL from environment or use default
|
||||
from litellm import anthropic_beta_headers_url
|
||||
|
||||
try:
|
||||
with open(config_path, "r") as f:
|
||||
_BETA_HEADERS_CONFIG = json.load(f)
|
||||
verbose_logger.debug(f"Loaded beta headers config from {config_path}")
|
||||
return _BETA_HEADERS_CONFIG
|
||||
except Exception as e:
|
||||
verbose_logger.error(f"Failed to load beta headers config: {e}")
|
||||
# Return empty config as fallback
|
||||
return {
|
||||
"anthropic": [],
|
||||
"azure_ai": [],
|
||||
"bedrock": [],
|
||||
"bedrock_converse": [],
|
||||
"vertex_ai": []
|
||||
}
|
||||
_BETA_HEADERS_CONFIG = get_beta_headers_config(url=anthropic_beta_headers_url)
|
||||
verbose_logger.debug("Loaded and cached beta headers config")
|
||||
|
||||
return _BETA_HEADERS_CONFIG
|
||||
|
||||
|
||||
def reload_beta_headers_config() -> Dict:
|
||||
"""
|
||||
Force reload the beta headers configuration from source (remote or local).
|
||||
Clears the cache and fetches fresh configuration.
|
||||
|
||||
Returns:
|
||||
Dict containing the newly loaded beta headers configuration
|
||||
"""
|
||||
global _BETA_HEADERS_CONFIG
|
||||
_BETA_HEADERS_CONFIG = None
|
||||
verbose_logger.info("Reloading beta headers config (cache cleared)")
|
||||
return _load_beta_headers_config()
|
||||
|
||||
|
||||
def get_provider_name(provider: str) -> str:
|
||||
|
|
@ -77,21 +218,19 @@ def filter_and_transform_beta_headers(
|
|||
provider: str,
|
||||
) -> List[str]:
|
||||
"""
|
||||
Filter beta headers based on provider's unsupported list.
|
||||
Filter and transform beta headers based on provider's mapping configuration.
|
||||
|
||||
This function:
|
||||
1. Removes headers that are in the provider's unsupported list
|
||||
2. Passes through all other headers as-is
|
||||
|
||||
Note: Header transformations/mappings (e.g., advanced-tool-use -> tool-search-tool)
|
||||
are handled in each provider's transformation code, not here.
|
||||
1. Only allows headers that are present in the provider's mapping keys
|
||||
2. Filters out headers with null values (unsupported)
|
||||
3. Maps headers to provider-specific names (e.g., advanced-tool-use -> tool-search-tool)
|
||||
|
||||
Args:
|
||||
beta_headers: List of Anthropic beta header values
|
||||
provider: Provider name (e.g., "anthropic", "bedrock", "vertex_ai")
|
||||
|
||||
Returns:
|
||||
List of filtered beta headers for the provider
|
||||
List of filtered and transformed beta headers for the provider
|
||||
"""
|
||||
if not beta_headers:
|
||||
return []
|
||||
|
|
@ -99,23 +238,33 @@ def filter_and_transform_beta_headers(
|
|||
config = _load_beta_headers_config()
|
||||
provider = get_provider_name(provider)
|
||||
|
||||
# Get unsupported headers for this provider
|
||||
unsupported_headers = set(config.get(provider, []))
|
||||
# Get the header mapping for this provider
|
||||
provider_mapping = config.get(provider, {})
|
||||
|
||||
filtered_headers: Set[str] = set()
|
||||
|
||||
for header in beta_headers:
|
||||
header = header.strip()
|
||||
|
||||
# Skip if header is unsupported
|
||||
if header in unsupported_headers:
|
||||
# Check if header is in the mapping
|
||||
if header not in provider_mapping:
|
||||
verbose_logger.debug(
|
||||
f"Dropping unknown beta header '{header}' for provider '{provider}' (not in mapping)"
|
||||
)
|
||||
continue
|
||||
|
||||
# Get the mapped header value
|
||||
mapped_header = provider_mapping[header]
|
||||
|
||||
# Skip if header is unsupported (null value)
|
||||
if mapped_header is None:
|
||||
verbose_logger.debug(
|
||||
f"Dropping unsupported beta header '{header}' for provider '{provider}'"
|
||||
)
|
||||
continue
|
||||
|
||||
# Pass through as-is
|
||||
filtered_headers.add(header)
|
||||
# Add the mapped header
|
||||
filtered_headers.add(mapped_header)
|
||||
|
||||
return sorted(list(filtered_headers))
|
||||
|
||||
|
|
@ -132,12 +281,14 @@ def is_beta_header_supported(
|
|||
provider: Provider name
|
||||
|
||||
Returns:
|
||||
True if the header is supported (not in unsupported list), False otherwise
|
||||
True if the header is in the mapping with a non-null value, False otherwise
|
||||
"""
|
||||
config = _load_beta_headers_config()
|
||||
provider = get_provider_name(provider)
|
||||
unsupported_headers = set(config.get(provider, []))
|
||||
return beta_header not in unsupported_headers
|
||||
provider_mapping = config.get(provider, {})
|
||||
|
||||
# Header is supported if it's in the mapping and has a non-null value
|
||||
return beta_header in provider_mapping and provider_mapping[beta_header] is not None
|
||||
|
||||
|
||||
def get_provider_beta_header(
|
||||
|
|
@ -145,27 +296,29 @@ def get_provider_beta_header(
|
|||
provider: str,
|
||||
) -> Optional[str]:
|
||||
"""
|
||||
Check if a beta header is supported by a provider.
|
||||
Get the provider-specific beta header name for a given Anthropic beta header.
|
||||
|
||||
Note: This does NOT handle header transformations/mappings.
|
||||
Those are handled in each provider's transformation code.
|
||||
This function handles header transformations/mappings (e.g., advanced-tool-use -> tool-search-tool).
|
||||
|
||||
Args:
|
||||
anthropic_beta_header: The Anthropic beta header value
|
||||
provider: Provider name
|
||||
|
||||
Returns:
|
||||
The original header if supported, or None if unsupported
|
||||
The provider-specific header name if supported, or None if unsupported/unknown
|
||||
"""
|
||||
config = _load_beta_headers_config()
|
||||
provider = get_provider_name(provider)
|
||||
|
||||
# Check if unsupported
|
||||
unsupported_headers = set(config.get(provider, []))
|
||||
if anthropic_beta_header in unsupported_headers:
|
||||
# Get the header mapping for this provider
|
||||
provider_mapping = config.get(provider, {})
|
||||
|
||||
# Check if header is in the mapping
|
||||
if anthropic_beta_header not in provider_mapping:
|
||||
return None
|
||||
|
||||
return anthropic_beta_header
|
||||
# Return the mapped value (could be None if unsupported)
|
||||
return provider_mapping[anthropic_beta_header]
|
||||
|
||||
|
||||
def update_headers_with_filtered_beta(
|
||||
|
|
@ -208,7 +361,7 @@ def update_headers_with_filtered_beta(
|
|||
|
||||
def get_unsupported_headers(provider: str) -> List[str]:
|
||||
"""
|
||||
Get all beta headers that are unsupported by a provider.
|
||||
Get all beta headers that are unsupported by a provider (have null values in mapping).
|
||||
|
||||
Args:
|
||||
provider: Provider name
|
||||
|
|
@ -218,4 +371,7 @@ def get_unsupported_headers(provider: str) -> List[str]:
|
|||
"""
|
||||
config = _load_beta_headers_config()
|
||||
provider = get_provider_name(provider)
|
||||
return config.get(provider, [])
|
||||
provider_mapping = config.get(provider, {})
|
||||
|
||||
# Return headers with null values
|
||||
return [header for header, value in provider_mapping.items() if value is None]
|
||||
|
|
|
|||
|
|
@ -237,17 +237,37 @@ def batch_completion_models_all_responses(*args, **kwargs):
|
|||
if "model" in kwargs:
|
||||
kwargs.pop("model")
|
||||
if "models" in kwargs:
|
||||
models = kwargs["models"]
|
||||
kwargs.pop("models")
|
||||
models = kwargs.pop("models")
|
||||
else:
|
||||
raise Exception("'models' param not in kwargs")
|
||||
|
||||
if isinstance(models, str):
|
||||
models = [models]
|
||||
elif isinstance(models, (list, tuple)):
|
||||
models = list(models)
|
||||
else:
|
||||
raise TypeError("'models' must be a string or list of strings")
|
||||
|
||||
if len(models) == 0:
|
||||
return []
|
||||
|
||||
responses = []
|
||||
|
||||
with concurrent.futures.ThreadPoolExecutor(max_workers=len(models)) as executor:
|
||||
for idx, model in enumerate(models):
|
||||
future = executor.submit(litellm.completion, *args, model=model, **kwargs)
|
||||
if future.result() is not None:
|
||||
responses.append(future.result())
|
||||
futures = [
|
||||
executor.submit(litellm.completion, *args, model=model, **kwargs)
|
||||
for model in models
|
||||
]
|
||||
|
||||
for future in futures:
|
||||
try:
|
||||
result = future.result()
|
||||
if result is not None:
|
||||
responses.append(result)
|
||||
except Exception as e:
|
||||
print_verbose(
|
||||
f"batch_completion_models_all_responses: model request failed: {str(e)}"
|
||||
)
|
||||
continue
|
||||
|
||||
return responses
|
||||
|
|
|
|||
|
|
@ -8,7 +8,7 @@ import litellm
|
|||
from litellm._logging import verbose_logger
|
||||
from litellm._uuid import uuid
|
||||
from litellm.types.llms.openai import Batch
|
||||
from litellm.types.utils import CallTypes, ModelResponse, Usage
|
||||
from litellm.types.utils import CallTypes, ModelInfo, ModelResponse, Usage
|
||||
from litellm.utils import token_counter
|
||||
|
||||
|
||||
|
|
@ -16,14 +16,22 @@ async def calculate_batch_cost_and_usage(
|
|||
file_content_dictionary: List[dict],
|
||||
custom_llm_provider: Literal["openai", "azure", "vertex_ai", "hosted_vllm", "anthropic"],
|
||||
model_name: Optional[str] = None,
|
||||
model_info: Optional[ModelInfo] = None,
|
||||
) -> Tuple[float, Usage, List[str]]:
|
||||
"""
|
||||
Calculate the cost and usage of a batch
|
||||
Calculate the cost and usage of a batch.
|
||||
|
||||
Args:
|
||||
model_info: Optional deployment-level model info with custom batch
|
||||
pricing. Threaded through to batch_cost_calculator so that
|
||||
deployment-specific pricing (e.g. input_cost_per_token_batches)
|
||||
is used instead of the global cost map.
|
||||
"""
|
||||
batch_cost = _batch_cost_calculator(
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
file_content_dictionary=file_content_dictionary,
|
||||
model_name=model_name,
|
||||
model_info=model_info,
|
||||
)
|
||||
batch_usage = _get_batch_job_total_usage_from_file_content(
|
||||
file_content_dictionary=file_content_dictionary,
|
||||
|
|
@ -39,11 +47,19 @@ async def _handle_completed_batch(
|
|||
batch: Batch,
|
||||
custom_llm_provider: Literal["openai", "azure", "vertex_ai", "hosted_vllm", "anthropic"],
|
||||
model_name: Optional[str] = None,
|
||||
litellm_params: Optional[dict] = None,
|
||||
) -> Tuple[float, Usage, List[str]]:
|
||||
"""Helper function to process a completed batch and handle logging"""
|
||||
"""Helper function to process a completed batch and handle logging
|
||||
|
||||
Args:
|
||||
batch: The batch object
|
||||
custom_llm_provider: The LLM provider
|
||||
model_name: Optional model name
|
||||
litellm_params: Optional litellm parameters containing credentials (api_key, api_base, etc.)
|
||||
"""
|
||||
# Get batch results
|
||||
file_content_dictionary = await _get_batch_output_file_content_as_dictionary(
|
||||
batch, custom_llm_provider
|
||||
batch, custom_llm_provider, litellm_params=litellm_params
|
||||
)
|
||||
|
||||
# Calculate costs and usage
|
||||
|
|
@ -86,6 +102,7 @@ def _batch_cost_calculator(
|
|||
file_content_dictionary: List[dict],
|
||||
custom_llm_provider: Literal["openai", "azure", "vertex_ai", "hosted_vllm", "anthropic"] = "openai",
|
||||
model_name: Optional[str] = None,
|
||||
model_info: Optional[ModelInfo] = None,
|
||||
) -> float:
|
||||
"""
|
||||
Calculate the cost of a batch based on the output file id
|
||||
|
|
@ -100,6 +117,7 @@ def _batch_cost_calculator(
|
|||
total_cost = _get_batch_job_cost_from_file_content(
|
||||
file_content_dictionary=file_content_dictionary,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
model_info=model_info,
|
||||
)
|
||||
verbose_logger.debug("total_cost=%s", total_cost)
|
||||
return total_cost
|
||||
|
|
@ -187,9 +205,16 @@ def calculate_vertex_ai_batch_cost_and_usage(
|
|||
async def _get_batch_output_file_content_as_dictionary(
|
||||
batch: Batch,
|
||||
custom_llm_provider: Literal["openai", "azure", "vertex_ai", "hosted_vllm", "anthropic"] = "openai",
|
||||
litellm_params: Optional[dict] = None,
|
||||
) -> List[dict]:
|
||||
"""
|
||||
Get the batch output file content as a list of dictionaries
|
||||
|
||||
Args:
|
||||
batch: The batch object
|
||||
custom_llm_provider: The LLM provider
|
||||
litellm_params: Optional litellm parameters containing credentials (api_key, api_base, etc.)
|
||||
Required for Azure and other providers that need authentication
|
||||
"""
|
||||
from litellm.files.main import afile_content
|
||||
from litellm.proxy.openai_files_endpoints.common_utils import (
|
||||
|
|
@ -211,13 +236,50 @@ async def _get_batch_output_file_content_as_dictionary(
|
|||
except (IndexError, AttributeError) as e:
|
||||
verbose_logger.error(f"Failed to extract LLM output file ID from unified file ID: {batch.output_file_id}, error: {e}")
|
||||
|
||||
_file_content = await afile_content(
|
||||
file_id=file_id,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
)
|
||||
# Build kwargs for afile_content with credentials from litellm_params
|
||||
file_content_kwargs = {
|
||||
"file_id": file_id,
|
||||
"custom_llm_provider": custom_llm_provider,
|
||||
}
|
||||
|
||||
# Extract and add credentials for file access
|
||||
credentials = _extract_file_access_credentials(litellm_params)
|
||||
file_content_kwargs.update(credentials)
|
||||
|
||||
_file_content = await afile_content(**file_content_kwargs)
|
||||
return _get_file_content_as_dictionary(_file_content.content)
|
||||
|
||||
|
||||
def _extract_file_access_credentials(litellm_params: Optional[dict]) -> dict:
|
||||
"""
|
||||
Extract credentials from litellm_params for file access operations.
|
||||
|
||||
This method extracts relevant authentication and configuration parameters
|
||||
needed for accessing files across different providers (Azure, Vertex AI, etc.).
|
||||
|
||||
Args:
|
||||
litellm_params: Dictionary containing litellm parameters with credentials
|
||||
|
||||
Returns:
|
||||
Dictionary containing only the credentials needed for file access
|
||||
"""
|
||||
credentials = {}
|
||||
|
||||
if litellm_params:
|
||||
# List of credential keys that should be passed to file operations
|
||||
credential_keys = [
|
||||
"api_key", "api_base", "api_version", "organization",
|
||||
"azure_ad_token", "azure_ad_token_provider",
|
||||
"vertex_project", "vertex_location", "vertex_credentials",
|
||||
"timeout", "max_retries"
|
||||
]
|
||||
for key in credential_keys:
|
||||
if key in litellm_params:
|
||||
credentials[key] = litellm_params[key]
|
||||
|
||||
return credentials
|
||||
|
||||
|
||||
def _get_file_content_as_dictionary(file_content: bytes) -> List[dict]:
|
||||
"""
|
||||
Get the file content as a list of dictionaries from JSON Lines format
|
||||
|
|
@ -238,10 +300,13 @@ def _get_file_content_as_dictionary(file_content: bytes) -> List[dict]:
|
|||
def _get_batch_job_cost_from_file_content(
|
||||
file_content_dictionary: List[dict],
|
||||
custom_llm_provider: Literal["openai", "azure", "vertex_ai", "hosted_vllm", "anthropic"] = "openai",
|
||||
model_info: Optional[ModelInfo] = None,
|
||||
) -> float:
|
||||
"""
|
||||
Get the cost of a batch job from the file content
|
||||
"""
|
||||
from litellm.cost_calculator import batch_cost_calculator
|
||||
|
||||
try:
|
||||
total_cost: float = 0.0
|
||||
# parse the file content as json
|
||||
|
|
@ -251,11 +316,22 @@ def _get_batch_job_cost_from_file_content(
|
|||
for _item in file_content_dictionary:
|
||||
if _batch_response_was_successful(_item):
|
||||
_response_body = _get_response_from_batch_job_output_file(_item)
|
||||
total_cost += litellm.completion_cost(
|
||||
completion_response=_response_body,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
call_type=CallTypes.aretrieve_batch.value,
|
||||
)
|
||||
if model_info is not None:
|
||||
usage = _get_batch_job_usage_from_response_body(_response_body)
|
||||
model = _response_body.get("model", "")
|
||||
prompt_cost, completion_cost = batch_cost_calculator(
|
||||
usage=usage,
|
||||
model=model,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
model_info=model_info,
|
||||
)
|
||||
total_cost += prompt_cost + completion_cost
|
||||
else:
|
||||
total_cost += litellm.completion_cost(
|
||||
completion_response=_response_body,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
call_type=CallTypes.aretrieve_batch.value,
|
||||
)
|
||||
verbose_logger.debug("total_cost=%s", total_cost)
|
||||
return total_cost
|
||||
except Exception as e:
|
||||
|
|
|
|||
|
|
@ -12,7 +12,8 @@ import asyncio
|
|||
import time
|
||||
import traceback
|
||||
from concurrent.futures import ThreadPoolExecutor
|
||||
from typing import TYPE_CHECKING, Any, List, Optional, Union
|
||||
from threading import Lock
|
||||
from typing import TYPE_CHECKING, Any, Dict, List, Optional, Tuple, Union
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from litellm.types.caching import RedisPipelineIncrementOperation
|
||||
|
|
@ -71,6 +72,7 @@ class DualCache(BaseCache):
|
|||
self.last_redis_batch_access_time = LimitedSizeOrderedDict(
|
||||
max_size=default_max_redis_batch_cache_size
|
||||
)
|
||||
self._last_redis_batch_access_time_lock = Lock()
|
||||
self.redis_batch_cache_expiry = (
|
||||
default_redis_batch_cache_expiry
|
||||
or litellm.default_redis_batch_cache_expiry
|
||||
|
|
@ -236,22 +238,46 @@ class DualCache(BaseCache):
|
|||
except Exception:
|
||||
verbose_logger.error(traceback.format_exc())
|
||||
|
||||
def get_redis_batch_keys(
|
||||
def _reserve_redis_batch_keys(
|
||||
self,
|
||||
current_time: float,
|
||||
keys: List[str],
|
||||
result: List[Any],
|
||||
) -> List[str]:
|
||||
sublist_keys = []
|
||||
for key, value in zip(keys, result):
|
||||
if value is None:
|
||||
) -> Tuple[List[str], Dict[str, Optional[float]]]:
|
||||
"""
|
||||
Atomically choose keys to fetch from Redis and reserve their access time.
|
||||
This prevents check-then-act races under concurrent async callers.
|
||||
"""
|
||||
sublist_keys: List[str] = []
|
||||
previous_access_times: Dict[str, Optional[float]] = {}
|
||||
|
||||
with self._last_redis_batch_access_time_lock:
|
||||
for key, value in zip(keys, result):
|
||||
if value is not None:
|
||||
continue
|
||||
|
||||
if (
|
||||
key not in self.last_redis_batch_access_time
|
||||
or current_time - self.last_redis_batch_access_time[key]
|
||||
>= self.redis_batch_cache_expiry
|
||||
):
|
||||
sublist_keys.append(key)
|
||||
return sublist_keys
|
||||
previous_access_times[key] = self.last_redis_batch_access_time.get(
|
||||
key
|
||||
)
|
||||
self.last_redis_batch_access_time[key] = current_time
|
||||
|
||||
return sublist_keys, previous_access_times
|
||||
|
||||
def _rollback_redis_batch_key_reservations(
|
||||
self, previous_access_times: Dict[str, Optional[float]]
|
||||
) -> None:
|
||||
with self._last_redis_batch_access_time_lock:
|
||||
for key, previous_time in previous_access_times.items():
|
||||
if previous_time is None:
|
||||
self.last_redis_batch_access_time.pop(key, None)
|
||||
else:
|
||||
self.last_redis_batch_access_time[key] = previous_time
|
||||
|
||||
async def async_batch_get_cache(
|
||||
self,
|
||||
|
|
@ -276,19 +302,23 @@ class DualCache(BaseCache):
|
|||
- check the redis cache
|
||||
"""
|
||||
current_time = time.time()
|
||||
sublist_keys = self.get_redis_batch_keys(current_time, keys, result)
|
||||
sublist_keys, previous_access_times = self._reserve_redis_batch_keys(
|
||||
current_time, keys, result
|
||||
)
|
||||
|
||||
# Only hit Redis if the last access time was more than 5 seconds ago
|
||||
# Only hit Redis if enough time has passed since last access.
|
||||
if len(sublist_keys) > 0:
|
||||
# If not found in in-memory cache, try fetching from Redis
|
||||
redis_result = await self.redis_cache.async_batch_get_cache(
|
||||
sublist_keys, parent_otel_span=parent_otel_span
|
||||
)
|
||||
|
||||
# Update the last access time for ALL queried keys
|
||||
# This includes keys with None values to throttle repeated Redis queries
|
||||
for key in sublist_keys:
|
||||
self.last_redis_batch_access_time[key] = current_time
|
||||
try:
|
||||
# If not found in in-memory cache, try fetching from Redis
|
||||
redis_result = await self.redis_cache.async_batch_get_cache(
|
||||
sublist_keys, parent_otel_span=parent_otel_span
|
||||
)
|
||||
except Exception:
|
||||
# Do not throttle subsequent callers if the Redis read fails.
|
||||
self._rollback_redis_batch_key_reservations(
|
||||
previous_access_times
|
||||
)
|
||||
raise
|
||||
|
||||
# Short-circuit if redis_result is None or contains only None values
|
||||
if redis_result is None or all(v is None for v in redis_result.values()):
|
||||
|
|
|
|||
|
|
@ -227,6 +227,84 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
|
||||
return input_items, instructions
|
||||
|
||||
def _map_optional_params_to_responses_api_request(
|
||||
self,
|
||||
optional_params: dict,
|
||||
responses_api_request: "ResponsesAPIOptionalRequestParams",
|
||||
) -> None:
|
||||
"""Map optional_params into responses_api_request (mutates in place)."""
|
||||
for key, value in optional_params.items():
|
||||
if value is None:
|
||||
continue
|
||||
if key in ("max_tokens", "max_completion_tokens"):
|
||||
responses_api_request["max_output_tokens"] = value
|
||||
elif key == "tools" and value is not None:
|
||||
responses_api_request["tools"] = (
|
||||
self._convert_tools_to_responses_format(
|
||||
cast(List[Dict[str, Any]], value)
|
||||
)
|
||||
)
|
||||
elif key == "response_format":
|
||||
text_format = self._transform_response_format_to_text_format(value)
|
||||
if text_format:
|
||||
responses_api_request["text"] = text_format # type: ignore
|
||||
elif key in ResponsesAPIOptionalRequestParams.__annotations__.keys():
|
||||
responses_api_request[key] = value # type: ignore
|
||||
elif key == "previous_response_id":
|
||||
responses_api_request["previous_response_id"] = value
|
||||
elif key == "reasoning_effort":
|
||||
responses_api_request["reasoning"] = self._map_reasoning_effort(value)
|
||||
elif key == "web_search_options":
|
||||
self._add_web_search_tool(responses_api_request, value)
|
||||
|
||||
def _build_sanitized_litellm_params(
|
||||
self, litellm_params: dict
|
||||
) -> Dict[str, Any]:
|
||||
"""Build sanitized litellm_params with merged metadata."""
|
||||
responses_optional_param_keys = set(
|
||||
ResponsesAPIOptionalRequestParams.__annotations__.keys()
|
||||
)
|
||||
sanitized: Dict[str, Any] = {
|
||||
key: value
|
||||
for key, value in litellm_params.items()
|
||||
if key not in responses_optional_param_keys
|
||||
}
|
||||
legacy_metadata = litellm_params.get("metadata")
|
||||
existing_litellm_metadata = litellm_params.get("litellm_metadata")
|
||||
merged_litellm_metadata: Dict[str, Any] = {}
|
||||
if isinstance(legacy_metadata, dict):
|
||||
merged_litellm_metadata.update(legacy_metadata)
|
||||
if isinstance(existing_litellm_metadata, dict):
|
||||
merged_litellm_metadata.update(existing_litellm_metadata)
|
||||
if merged_litellm_metadata:
|
||||
sanitized["litellm_metadata"] = merged_litellm_metadata
|
||||
else:
|
||||
sanitized.pop("litellm_metadata", None)
|
||||
return sanitized
|
||||
|
||||
def _merge_responses_api_request_into_request_data(
|
||||
self,
|
||||
request_data: Dict[str, Any],
|
||||
responses_api_request: "ResponsesAPIOptionalRequestParams",
|
||||
instructions: Optional[str],
|
||||
) -> None:
|
||||
"""Add non-None values from responses_api_request into request_data."""
|
||||
for key, value in responses_api_request.items():
|
||||
if value is None:
|
||||
continue
|
||||
if key == "instructions" and instructions:
|
||||
request_data["instructions"] = instructions
|
||||
elif key == "stream_options" and isinstance(value, dict):
|
||||
request_data["stream_options"] = value.get("include_obfuscation")
|
||||
elif key == "user" and isinstance(value, str):
|
||||
# OpenAI API requires user param to be max 64 chars - truncate if longer
|
||||
if len(value) <= 64:
|
||||
request_data["user"] = value
|
||||
else:
|
||||
request_data["user"] = value[:64]
|
||||
else:
|
||||
request_data[key] = value
|
||||
|
||||
def transform_request(
|
||||
self,
|
||||
model: str,
|
||||
|
|
@ -251,36 +329,10 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
if instructions:
|
||||
responses_api_request["instructions"] = instructions
|
||||
|
||||
# Map optional parameters
|
||||
for key, value in optional_params.items():
|
||||
if value is None:
|
||||
continue
|
||||
if key in ("max_tokens", "max_completion_tokens"):
|
||||
responses_api_request["max_output_tokens"] = value
|
||||
elif key == "tools" and value is not None:
|
||||
# Convert chat completion tools to responses API tools format
|
||||
responses_api_request["tools"] = (
|
||||
self._convert_tools_to_responses_format(
|
||||
cast(List[Dict[str, Any]], value)
|
||||
)
|
||||
)
|
||||
elif key == "response_format":
|
||||
# Convert response_format to text.format
|
||||
text_format = self._transform_response_format_to_text_format(value)
|
||||
if text_format:
|
||||
responses_api_request["text"] = text_format # type: ignore
|
||||
elif key in ResponsesAPIOptionalRequestParams.__annotations__.keys():
|
||||
responses_api_request[key] = value # type: ignore
|
||||
elif key == "metadata":
|
||||
responses_api_request["metadata"] = value
|
||||
elif key == "previous_response_id":
|
||||
responses_api_request["previous_response_id"] = value
|
||||
elif key == "reasoning_effort":
|
||||
responses_api_request["reasoning"] = self._map_reasoning_effort(value)
|
||||
elif key == "web_search_options":
|
||||
self._add_web_search_tool(responses_api_request, value)
|
||||
self._map_optional_params_to_responses_api_request(
|
||||
optional_params, responses_api_request
|
||||
)
|
||||
|
||||
# Get stream parameter from litellm_params if not in optional_params
|
||||
stream = optional_params.get("stream") or litellm_params.get("stream", False)
|
||||
verbose_logger.debug(f"Chat provider: Stream parameter: {stream}")
|
||||
|
||||
|
|
@ -304,11 +356,15 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
|
||||
setattr(litellm_logging_obj, "call_type", CallTypes.responses.value)
|
||||
|
||||
sanitized_litellm_params = self._build_sanitized_litellm_params(
|
||||
litellm_params
|
||||
)
|
||||
|
||||
request_data = {
|
||||
"model": api_model,
|
||||
"input": input_items,
|
||||
"litellm_logging_obj": litellm_logging_obj,
|
||||
**litellm_params,
|
||||
**sanitized_litellm_params,
|
||||
"client": client,
|
||||
}
|
||||
|
||||
|
|
@ -316,18 +372,9 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
f"Chat provider: Final request model={api_model}, input_items={len(input_items)}"
|
||||
)
|
||||
|
||||
# Add non-None values from responses_api_request
|
||||
for key, value in responses_api_request.items():
|
||||
if value is not None:
|
||||
if key == "instructions" and instructions:
|
||||
request_data["instructions"] = instructions
|
||||
elif key == "stream_options" and isinstance(value, dict):
|
||||
request_data["stream_options"] = value.get("include_obfuscation")
|
||||
elif key == "user": # string can't be longer than 64 characters
|
||||
if isinstance(value, str) and len(value) <= 64:
|
||||
request_data["user"] = value
|
||||
else:
|
||||
request_data[key] = value
|
||||
self._merge_responses_api_request_into_request_data(
|
||||
request_data, responses_api_request, instructions
|
||||
)
|
||||
|
||||
if headers:
|
||||
request_data["extra_headers"] = headers
|
||||
|
|
|
|||
|
|
@ -101,9 +101,12 @@ MCP_OAUTH2_TOKEN_CACHE_MAX_SIZE = int(
|
|||
MCP_OAUTH2_TOKEN_CACHE_DEFAULT_TTL = int(
|
||||
os.getenv("MCP_OAUTH2_TOKEN_CACHE_DEFAULT_TTL", "3600")
|
||||
)
|
||||
MCP_OAUTH2_TOKEN_CACHE_MIN_TTL = int(
|
||||
os.getenv("MCP_OAUTH2_TOKEN_CACHE_MIN_TTL", "10")
|
||||
)
|
||||
|
||||
# Default npm cache directory for STDIO MCP servers.
|
||||
# npm/npx needs a writable cache dir; in containers the default (~/.npm)
|
||||
# may not exist or be read-only. /tmp is always writable.
|
||||
MCP_NPM_CACHE_DIR = os.getenv("MCP_NPM_CACHE_DIR", "/tmp/.npm_mcp_cache")
|
||||
MCP_OAUTH2_TOKEN_CACHE_MIN_TTL = int(os.getenv("MCP_OAUTH2_TOKEN_CACHE_MIN_TTL", "10"))
|
||||
|
||||
LITELLM_UI_ALLOW_HEADERS = [
|
||||
"x-litellm-semantic-filter",
|
||||
|
|
@ -126,7 +129,7 @@ DEFAULT_REASONING_EFFORT_MINIMAL_THINKING_BUDGET_GEMINI_2_5_FLASH_LITE = int(
|
|||
# Maximum number of callbacks that can be registered
|
||||
# This prevents callbacks from exponentially growing and consuming CPU resources
|
||||
# Override with LITELLM_MAX_CALLBACKS env var for large deployments (e.g., many teams with guardrails)
|
||||
MAX_CALLBACKS = get_env_int("LITELLM_MAX_CALLBACKS", 30)
|
||||
MAX_CALLBACKS = get_env_int("LITELLM_MAX_CALLBACKS", 100)
|
||||
|
||||
# Generic fallback for unknown models
|
||||
DEFAULT_REASONING_EFFORT_MINIMAL_THINKING_BUDGET = int(
|
||||
|
|
@ -162,15 +165,19 @@ _DEFAULT_TTL_FOR_HTTPX_CLIENTS = 3600 # 1 hour, re-use the same httpx client fo
|
|||
# Aiohttp connection pooling - prevents memory leaks from unbounded connection growth
|
||||
# Set to 0 for unlimited (not recommended for production)
|
||||
AIOHTTP_CONNECTOR_LIMIT = int(os.getenv("AIOHTTP_CONNECTOR_LIMIT", 300))
|
||||
AIOHTTP_CONNECTOR_LIMIT_PER_HOST = int(os.getenv("AIOHTTP_CONNECTOR_LIMIT_PER_HOST", 50))
|
||||
AIOHTTP_CONNECTOR_LIMIT_PER_HOST = int(
|
||||
os.getenv("AIOHTTP_CONNECTOR_LIMIT_PER_HOST", 50)
|
||||
)
|
||||
AIOHTTP_KEEPALIVE_TIMEOUT = int(os.getenv("AIOHTTP_KEEPALIVE_TIMEOUT", 120))
|
||||
AIOHTTP_TTL_DNS_CACHE = int(os.getenv("AIOHTTP_TTL_DNS_CACHE", 300))
|
||||
# enable_cleanup_closed is only needed for Python versions with the SSL leak bug
|
||||
# Fixed in Python 3.12.7+ and 3.13.1+ (see https://github.com/python/cpython/pull/118960)
|
||||
# Reference: https://github.com/aio-libs/aiohttp/blob/master/aiohttp/connector.py#L74-L78
|
||||
AIOHTTP_NEEDS_CLEANUP_CLOSED = (
|
||||
(3, 13, 0) <= sys.version_info < (3, 13, 1) or sys.version_info < (3, 12, 7)
|
||||
)
|
||||
AIOHTTP_NEEDS_CLEANUP_CLOSED = (3, 13, 0) <= sys.version_info < (
|
||||
3,
|
||||
13,
|
||||
1,
|
||||
) or sys.version_info < (3, 12, 7)
|
||||
|
||||
# WebSocket constants
|
||||
# Default to None (unlimited) to match OpenAI's official agents SDK behavior
|
||||
|
|
@ -208,11 +215,15 @@ REDIS_UPDATE_BUFFER_KEY = "litellm_spend_update_buffer"
|
|||
REDIS_DAILY_SPEND_UPDATE_BUFFER_KEY = "litellm_daily_spend_update_buffer"
|
||||
REDIS_DAILY_TEAM_SPEND_UPDATE_BUFFER_KEY = "litellm_daily_team_spend_update_buffer"
|
||||
REDIS_DAILY_ORG_SPEND_UPDATE_BUFFER_KEY = "litellm_daily_org_spend_update_buffer"
|
||||
REDIS_DAILY_END_USER_SPEND_UPDATE_BUFFER_KEY = "litellm_daily_end_user_spend_update_buffer"
|
||||
REDIS_DAILY_END_USER_SPEND_UPDATE_BUFFER_KEY = (
|
||||
"litellm_daily_end_user_spend_update_buffer"
|
||||
)
|
||||
REDIS_DAILY_AGENT_SPEND_UPDATE_BUFFER_KEY = "litellm_daily_agent_spend_update_buffer"
|
||||
REDIS_DAILY_TAG_SPEND_UPDATE_BUFFER_KEY = "litellm_daily_tag_spend_update_buffer"
|
||||
MAX_REDIS_BUFFER_DEQUEUE_COUNT = int(os.getenv("MAX_REDIS_BUFFER_DEQUEUE_COUNT", 100))
|
||||
MAX_SIZE_IN_MEMORY_QUEUE = int(os.getenv("MAX_SIZE_IN_MEMORY_QUEUE", 2000))
|
||||
# Bounds asyncio.Queue() instances (log queues, spend update queues, etc.) to prevent unbounded memory growth
|
||||
LITELLM_ASYNCIO_QUEUE_MAXSIZE = int(os.getenv("LITELLM_ASYNCIO_QUEUE_MAXSIZE", 1000))
|
||||
MAX_IN_MEMORY_QUEUE_FLUSH_COUNT = int(
|
||||
os.getenv("MAX_IN_MEMORY_QUEUE_FLUSH_COUNT", 1000)
|
||||
)
|
||||
|
|
@ -308,6 +319,9 @@ NON_LLM_CONNECTION_TIMEOUT = int(
|
|||
MAX_EXCEPTION_MESSAGE_LENGTH = int(os.getenv("MAX_EXCEPTION_MESSAGE_LENGTH", 2000))
|
||||
MAX_STRING_LENGTH_PROMPT_IN_DB = int(os.getenv("MAX_STRING_LENGTH_PROMPT_IN_DB", 2048))
|
||||
BEDROCK_MAX_POLICY_SIZE = int(os.getenv("BEDROCK_MAX_POLICY_SIZE", 75))
|
||||
BEDROCK_MIN_THINKING_BUDGET_TOKENS = int(
|
||||
os.getenv("BEDROCK_MIN_THINKING_BUDGET_TOKENS", 1024)
|
||||
)
|
||||
REPLICATE_POLLING_DELAY_SECONDS = float(
|
||||
os.getenv("REPLICATE_POLLING_DELAY_SECONDS", 0.5)
|
||||
)
|
||||
|
|
@ -334,7 +348,9 @@ MAX_SIZE_PER_ITEM_IN_MEMORY_CACHE_IN_KB = int(
|
|||
DEFAULT_MAX_TOKENS_FOR_TRITON = int(os.getenv("DEFAULT_MAX_TOKENS_FOR_TRITON", 2000))
|
||||
#### Networking settings ####
|
||||
request_timeout: float = float(os.getenv("REQUEST_TIMEOUT", 6000)) # time in seconds
|
||||
DEFAULT_A2A_AGENT_TIMEOUT: float = float(os.getenv("DEFAULT_A2A_AGENT_TIMEOUT", 6000)) # 10 minutes
|
||||
DEFAULT_A2A_AGENT_TIMEOUT: float = float(
|
||||
os.getenv("DEFAULT_A2A_AGENT_TIMEOUT", 6000)
|
||||
) # 10 minutes
|
||||
# Patterns that indicate a localhost/internal URL in A2A agent cards that should be
|
||||
# replaced with the original base_url. This is a common misconfiguration where
|
||||
# developers deploy agents with development URLs in their agent cards.
|
||||
|
|
@ -386,8 +402,12 @@ DD_TRACER_STREAMING_CHUNK_YIELD_RESOURCE = os.getenv(
|
|||
"DD_TRACER_STREAMING_CHUNK_YIELD_RESOURCE", "streaming.chunk.yield"
|
||||
)
|
||||
|
||||
EMAIL_BUDGET_ALERT_TTL = int(os.getenv("EMAIL_BUDGET_ALERT_TTL", 24 * 60 * 60)) # 24 hours in seconds
|
||||
EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE = float(os.getenv("EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE", 0.8)) # 80% of max budget
|
||||
EMAIL_BUDGET_ALERT_TTL = int(
|
||||
os.getenv("EMAIL_BUDGET_ALERT_TTL", 24 * 60 * 60)
|
||||
) # 24 hours in seconds
|
||||
EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE = float(
|
||||
os.getenv("EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE", 0.8)
|
||||
) # 80% of max budget
|
||||
############### LLM Provider Constants ###############
|
||||
### ANTHROPIC CONSTANTS ###
|
||||
ANTHROPIC_TOKEN_COUNTING_BETA_VERSION = os.getenv(
|
||||
|
|
@ -1007,10 +1027,12 @@ BEDROCK_EMBEDDING_PROVIDERS_LITERAL = Literal[
|
|||
|
||||
BEDROCK_CONVERSE_MODELS = [
|
||||
"qwen.qwen3-coder-480b-a35b-v1:0",
|
||||
"qwen.qwen3-coder-next",
|
||||
"qwen.qwen3-235b-a22b-2507-v1:0",
|
||||
"qwen.qwen3-coder-30b-a3b-v1:0",
|
||||
"qwen.qwen3-32b-v1:0",
|
||||
"deepseek.v3-v1:0",
|
||||
"deepseek.v3.2",
|
||||
"openai.gpt-oss-20b-1:0",
|
||||
"openai.gpt-oss-120b-1:0",
|
||||
"anthropic.claude-haiku-4-5-20251001-v1:0",
|
||||
|
|
@ -1053,6 +1075,8 @@ BEDROCK_CONVERSE_MODELS = [
|
|||
"amazon.nova-pro-v1:0",
|
||||
"writer.palmyra-x4-v1:0",
|
||||
"writer.palmyra-x5-v1:0",
|
||||
"minimax.minimax-m2.1",
|
||||
"moonshotai.kimi-k2.5",
|
||||
]
|
||||
|
||||
|
||||
|
|
@ -1137,7 +1161,17 @@ known_tokenizer_config = {
|
|||
}
|
||||
|
||||
|
||||
OPENAI_FINISH_REASONS = ["stop", "length", "function_call", "content_filter", "null", "finish_reason_unspecified", "malformed_function_call", "guardrail_intervened", "eos"]
|
||||
OPENAI_FINISH_REASONS = [
|
||||
"stop",
|
||||
"length",
|
||||
"function_call",
|
||||
"content_filter",
|
||||
"null",
|
||||
"finish_reason_unspecified",
|
||||
"malformed_function_call",
|
||||
"guardrail_intervened",
|
||||
"eos",
|
||||
]
|
||||
HUMANLOOP_PROMPT_CACHE_TTL_SECONDS = int(
|
||||
os.getenv("HUMANLOOP_PROMPT_CACHE_TTL_SECONDS", 60)
|
||||
) # 1 minute
|
||||
|
|
@ -1227,6 +1261,9 @@ LITELLM_KEY_ROTATION_ENABLED = os.getenv("LITELLM_KEY_ROTATION_ENABLED", "false"
|
|||
LITELLM_KEY_ROTATION_CHECK_INTERVAL_SECONDS = int(
|
||||
os.getenv("LITELLM_KEY_ROTATION_CHECK_INTERVAL_SECONDS", 86400)
|
||||
) # 24 hours default
|
||||
LITELLM_KEY_ROTATION_GRACE_PERIOD: str = os.getenv(
|
||||
"LITELLM_KEY_ROTATION_GRACE_PERIOD", ""
|
||||
) # Duration to keep old key valid after rotation (e.g. "24h", "2d"); empty = immediate revoke (default)
|
||||
UI_SESSION_TOKEN_TEAM_ID = "litellm-dashboard"
|
||||
LITELLM_PROXY_ADMIN_NAME = "default_user_id"
|
||||
|
||||
|
|
@ -1237,8 +1274,8 @@ CLI_SSO_SESSION_CACHE_KEY_PREFIX = "cli_sso_session"
|
|||
CLI_JWT_TOKEN_NAME = "cli-jwt-token"
|
||||
# Support both CLI_JWT_EXPIRATION_HOURS and LITELLM_CLI_JWT_EXPIRATION_HOURS for backwards compatibility
|
||||
CLI_JWT_EXPIRATION_HOURS = int(
|
||||
os.getenv("CLI_JWT_EXPIRATION_HOURS")
|
||||
or os.getenv("LITELLM_CLI_JWT_EXPIRATION_HOURS")
|
||||
os.getenv("CLI_JWT_EXPIRATION_HOURS")
|
||||
or os.getenv("LITELLM_CLI_JWT_EXPIRATION_HOURS")
|
||||
or 24
|
||||
)
|
||||
|
||||
|
|
@ -1306,6 +1343,9 @@ DEFAULT_SLACK_ALERTING_THRESHOLD = int(
|
|||
os.getenv("DEFAULT_SLACK_ALERTING_THRESHOLD", 300)
|
||||
)
|
||||
MAX_TEAM_LIST_LIMIT = int(os.getenv("MAX_TEAM_LIST_LIMIT", 20))
|
||||
MAX_POLICY_ESTIMATE_IMPACT_ROWS = int(
|
||||
os.getenv("MAX_POLICY_ESTIMATE_IMPACT_ROWS", 1000)
|
||||
)
|
||||
DEFAULT_PROMPT_INJECTION_SIMILARITY_THRESHOLD = float(
|
||||
os.getenv("DEFAULT_PROMPT_INJECTION_SIMILARITY_THRESHOLD", 0.7)
|
||||
)
|
||||
|
|
@ -1326,6 +1366,9 @@ SPECIAL_LITELLM_AUTH_TOKEN = ["ui-token"]
|
|||
DEFAULT_MANAGEMENT_OBJECT_IN_MEMORY_CACHE_TTL = int(
|
||||
os.getenv("DEFAULT_MANAGEMENT_OBJECT_IN_MEMORY_CACHE_TTL", 60)
|
||||
)
|
||||
DEFAULT_ACCESS_GROUP_CACHE_TTL = int(
|
||||
os.getenv("DEFAULT_ACCESS_GROUP_CACHE_TTL", 600)
|
||||
)
|
||||
|
||||
# Sentry Scrubbing Configuration
|
||||
SENTRY_DENYLIST = [
|
||||
|
|
@ -1416,9 +1459,7 @@ MICROSOFT_USER_EMAIL_ATTRIBUTE = str(
|
|||
MICROSOFT_USER_DISPLAY_NAME_ATTRIBUTE = str(
|
||||
os.getenv("MICROSOFT_USER_DISPLAY_NAME_ATTRIBUTE", "displayName")
|
||||
)
|
||||
MICROSOFT_USER_ID_ATTRIBUTE = str(
|
||||
os.getenv("MICROSOFT_USER_ID_ATTRIBUTE", "id")
|
||||
)
|
||||
MICROSOFT_USER_ID_ATTRIBUTE = str(os.getenv("MICROSOFT_USER_ID_ATTRIBUTE", "id"))
|
||||
MICROSOFT_USER_FIRST_NAME_ATTRIBUTE = str(
|
||||
os.getenv("MICROSOFT_USER_FIRST_NAME_ATTRIBUTE", "givenName")
|
||||
)
|
||||
|
|
|
|||
|
|
@ -74,6 +74,7 @@ from litellm.llms.vertex_ai.cost_calculator import (
|
|||
from litellm.llms.vertex_ai.cost_calculator import cost_router as google_cost_router
|
||||
from litellm.llms.xai.cost_calculator import cost_per_token as xai_cost_per_token
|
||||
from litellm.responses.utils import ResponseAPILoggingUtils
|
||||
from litellm.types.agents import LiteLLMSendMessageResponse
|
||||
from litellm.types.llms.openai import (
|
||||
HttpxBinaryResponseContent,
|
||||
ImageGenerationRequestQuality,
|
||||
|
|
@ -150,32 +151,33 @@ def _get_additional_costs(
|
|||
) -> Optional[dict]:
|
||||
"""
|
||||
Calculate additional costs beyond standard token costs.
|
||||
|
||||
|
||||
This function delegates to provider-specific config classes to calculate
|
||||
any additional costs like routing fees, infrastructure costs, etc.
|
||||
|
||||
|
||||
Args:
|
||||
model: The model name
|
||||
custom_llm_provider: The provider name (optional)
|
||||
prompt_tokens: Number of prompt tokens
|
||||
completion_tokens: Number of completion tokens
|
||||
|
||||
|
||||
Returns:
|
||||
Optional dictionary with cost names and amounts, or None if no additional costs
|
||||
"""
|
||||
if not custom_llm_provider:
|
||||
return None
|
||||
|
||||
|
||||
try:
|
||||
config_class = None
|
||||
if custom_llm_provider == "azure_ai":
|
||||
from litellm.llms.azure_ai.common_utils import AzureFoundryModelInfo
|
||||
|
||||
config_class = AzureFoundryModelInfo.get_azure_ai_config_for_model(model)
|
||||
# Add more providers here as needed
|
||||
# elif custom_llm_provider == "other_provider":
|
||||
# config_class = get_other_provider_config(model)
|
||||
|
||||
if config_class and hasattr(config_class, 'calculate_additional_costs'):
|
||||
|
||||
if config_class and hasattr(config_class, "calculate_additional_costs"):
|
||||
return config_class.calculate_additional_costs(
|
||||
model=model,
|
||||
prompt_tokens=prompt_tokens,
|
||||
|
|
@ -183,7 +185,7 @@ def _get_additional_costs(
|
|||
)
|
||||
except Exception as e:
|
||||
verbose_logger.debug(f"Error calculating additional costs: {e}")
|
||||
|
||||
|
||||
return None
|
||||
|
||||
|
||||
|
|
@ -748,6 +750,8 @@ def _infer_call_type(
|
|||
return "image_generation"
|
||||
elif isinstance(completion_response, TextCompletionResponse):
|
||||
return "text_completion"
|
||||
elif isinstance(completion_response, LiteLLMSendMessageResponse):
|
||||
return "send_message"
|
||||
|
||||
return call_type
|
||||
|
||||
|
|
@ -1037,9 +1041,9 @@ def completion_cost( # noqa: PLR0915
|
|||
or isinstance(completion_response, dict)
|
||||
): # tts returns a custom class
|
||||
if isinstance(completion_response, dict):
|
||||
usage_obj: Optional[
|
||||
Union[dict, Usage]
|
||||
] = completion_response.get("usage", {})
|
||||
usage_obj: Optional[Union[dict, Usage]] = (
|
||||
completion_response.get("usage", {})
|
||||
)
|
||||
else:
|
||||
usage_obj = getattr(completion_response, "usage", {})
|
||||
if isinstance(usage_obj, BaseModel) and not _is_known_usage_objects(
|
||||
|
|
@ -1393,7 +1397,7 @@ def completion_cost( # noqa: PLR0915
|
|||
service_tier=service_tier,
|
||||
response=completion_response,
|
||||
)
|
||||
|
||||
|
||||
# Get additional costs from provider (e.g., routing fees, infrastructure costs)
|
||||
additional_costs = _get_additional_costs(
|
||||
model=model,
|
||||
|
|
@ -1401,7 +1405,7 @@ def completion_cost( # noqa: PLR0915
|
|||
prompt_tokens=prompt_tokens,
|
||||
completion_tokens=completion_tokens,
|
||||
)
|
||||
|
||||
|
||||
_final_cost = (
|
||||
prompt_tokens_cost_usd_dollar + completion_tokens_cost_usd_dollar
|
||||
)
|
||||
|
|
@ -1892,9 +1896,16 @@ def batch_cost_calculator(
|
|||
usage: Usage,
|
||||
model: str,
|
||||
custom_llm_provider: Optional[str] = None,
|
||||
model_info: Optional[ModelInfo] = None,
|
||||
) -> Tuple[float, float]:
|
||||
"""
|
||||
Calculate the cost of a batch job
|
||||
Calculate the cost of a batch job.
|
||||
|
||||
Args:
|
||||
model_info: Optional deployment-level model info containing custom
|
||||
batch pricing (e.g. input_cost_per_token_batches). When provided,
|
||||
skips the global litellm.get_model_info() lookup so that
|
||||
deployment-specific pricing is used.
|
||||
"""
|
||||
|
||||
_, custom_llm_provider, _, _ = litellm.get_llm_provider(
|
||||
|
|
@ -1907,12 +1918,13 @@ def batch_cost_calculator(
|
|||
custom_llm_provider,
|
||||
)
|
||||
|
||||
try:
|
||||
model_info: Optional[ModelInfo] = litellm.get_model_info(
|
||||
model=model, custom_llm_provider=custom_llm_provider
|
||||
)
|
||||
except Exception:
|
||||
model_info = None
|
||||
if model_info is None:
|
||||
try:
|
||||
model_info = litellm.get_model_info(
|
||||
model=model, custom_llm_provider=custom_llm_provider
|
||||
)
|
||||
except Exception:
|
||||
model_info = None
|
||||
|
||||
if not model_info:
|
||||
return 0.0, 0.0
|
||||
|
|
|
|||
|
|
@ -28,6 +28,41 @@ else:
|
|||
|
||||
|
||||
class ArizeLogger(OpenTelemetry):
|
||||
"""
|
||||
Arize logger that sends traces to an Arize endpoint.
|
||||
|
||||
Creates its own dedicated TracerProvider so it can coexist with the
|
||||
generic ``otel`` callback (or any other OTEL-based integration) without
|
||||
fighting over the global ``opentelemetry.trace`` TracerProvider singleton.
|
||||
"""
|
||||
|
||||
def _init_tracing(self, tracer_provider):
|
||||
"""
|
||||
Override to always create a *private* TracerProvider for Arize.
|
||||
|
||||
See ArizePhoenixLogger._init_tracing for full rationale.
|
||||
"""
|
||||
from opentelemetry.sdk.trace import TracerProvider
|
||||
from opentelemetry.trace import SpanKind
|
||||
|
||||
if tracer_provider is not None:
|
||||
self.tracer = tracer_provider.get_tracer("litellm")
|
||||
self.span_kind = SpanKind
|
||||
return
|
||||
|
||||
provider = TracerProvider(resource=self._get_litellm_resource(self.config))
|
||||
provider.add_span_processor(self._get_span_processor())
|
||||
self.tracer = provider.get_tracer("litellm")
|
||||
self.span_kind = SpanKind
|
||||
|
||||
def _init_otel_logger_on_litellm_proxy(self):
|
||||
"""
|
||||
Override: Arize should NOT overwrite the proxy's
|
||||
``open_telemetry_logger``. That attribute is reserved for the
|
||||
primary ``otel`` callback which handles proxy-level parent spans.
|
||||
"""
|
||||
pass
|
||||
|
||||
def set_attributes(self, span: Span, kwargs, response_obj: Optional[Any]):
|
||||
ArizeLogger.set_arize_attributes(span, kwargs, response_obj)
|
||||
return
|
||||
|
|
|
|||
|
|
@ -5,43 +5,211 @@ from litellm._logging import verbose_logger
|
|||
from litellm.integrations.arize import _utils
|
||||
from litellm.integrations.arize._utils import ArizeOTELAttributes
|
||||
from litellm.types.integrations.arize_phoenix import ArizePhoenixConfig
|
||||
from litellm.integrations.opentelemetry import OpenTelemetry
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from opentelemetry.sdk.trace import TracerProvider
|
||||
from opentelemetry.trace import Span as _Span
|
||||
from opentelemetry.trace import SpanKind
|
||||
|
||||
from litellm.integrations.opentelemetry import OpenTelemetry as _OpenTelemetry
|
||||
from litellm.integrations.opentelemetry import OpenTelemetryConfig as _OpenTelemetryConfig
|
||||
from litellm.types.integrations.arize import Protocol as _Protocol
|
||||
|
||||
Protocol = _Protocol
|
||||
OpenTelemetryConfig = _OpenTelemetryConfig
|
||||
Span = Union[_Span, Any]
|
||||
OpenTelemetry = _OpenTelemetry
|
||||
else:
|
||||
Protocol = Any
|
||||
OpenTelemetryConfig = Any
|
||||
Span = Any
|
||||
TracerProvider = Any
|
||||
SpanKind = Any
|
||||
# Import OpenTelemetry at runtime
|
||||
try:
|
||||
from litellm.integrations.opentelemetry import OpenTelemetry
|
||||
except ImportError:
|
||||
OpenTelemetry = None # type: ignore
|
||||
|
||||
|
||||
ARIZE_HOSTED_PHOENIX_ENDPOINT = "https://otlp.arize.com/v1/traces"
|
||||
|
||||
|
||||
class ArizePhoenixLogger(OpenTelemetry):
|
||||
class ArizePhoenixLogger(OpenTelemetry): # type: ignore
|
||||
"""
|
||||
Arize Phoenix logger that sends traces to a Phoenix endpoint.
|
||||
|
||||
Creates its own dedicated TracerProvider so it can coexist with the
|
||||
generic ``otel`` callback (or any other OTEL-based integration) without
|
||||
fighting over the global ``opentelemetry.trace`` TracerProvider singleton.
|
||||
"""
|
||||
|
||||
def _init_tracing(self, tracer_provider):
|
||||
"""
|
||||
Override to always create a *private* TracerProvider for Arize Phoenix.
|
||||
|
||||
The base ``OpenTelemetry._init_tracing`` falls back to the global
|
||||
TracerProvider when one already exists. That causes whichever
|
||||
integration initialises second to silently reuse the first one's
|
||||
exporter, so spans only reach one destination.
|
||||
|
||||
By creating our own provider we guarantee Arize Phoenix always gets
|
||||
its own exporter pipeline, regardless of initialisation order.
|
||||
"""
|
||||
from opentelemetry.sdk.trace import TracerProvider
|
||||
from opentelemetry.trace import SpanKind
|
||||
|
||||
if tracer_provider is not None:
|
||||
# Explicitly supplied (e.g. in tests) — honour it.
|
||||
self.tracer = tracer_provider.get_tracer("litellm")
|
||||
self.span_kind = SpanKind
|
||||
return
|
||||
|
||||
# Always create a dedicated provider — never touch the global one.
|
||||
provider = TracerProvider(resource=self._get_litellm_resource(self.config))
|
||||
provider.add_span_processor(self._get_span_processor())
|
||||
self.tracer = provider.get_tracer("litellm")
|
||||
self.span_kind = SpanKind
|
||||
verbose_logger.debug(
|
||||
"ArizePhoenixLogger: Created dedicated TracerProvider "
|
||||
"(endpoint=%s, exporter=%s)",
|
||||
self.config.endpoint,
|
||||
self.config.exporter,
|
||||
)
|
||||
|
||||
def _init_otel_logger_on_litellm_proxy(self):
|
||||
"""
|
||||
Override: Arize Phoenix should NOT overwrite the proxy's
|
||||
``open_telemetry_logger``. That attribute is reserved for the
|
||||
primary ``otel`` callback which handles proxy-level parent spans.
|
||||
"""
|
||||
pass
|
||||
|
||||
def set_attributes(self, span: Span, kwargs, response_obj: Optional[Any]):
|
||||
ArizePhoenixLogger.set_arize_phoenix_attributes(span, kwargs, response_obj)
|
||||
return
|
||||
|
||||
@staticmethod
|
||||
def set_arize_phoenix_attributes(span: Span, kwargs, response_obj):
|
||||
from litellm.integrations.opentelemetry_utils.base_otel_llm_obs_attributes import safe_set_attribute
|
||||
|
||||
_utils.set_attributes(span, kwargs, response_obj, ArizeOTELAttributes)
|
||||
|
||||
# Set project name on the span for all traces to go to custom Phoenix projects
|
||||
config = ArizePhoenixLogger.get_arize_phoenix_config()
|
||||
if config.project_name:
|
||||
from litellm.integrations.opentelemetry_utils.base_otel_llm_obs_attributes import safe_set_attribute
|
||||
safe_set_attribute(span, "openinference.project.name", config.project_name)
|
||||
|
||||
|
||||
# Dynamic project name: check metadata first, then fall back to env var config
|
||||
dynamic_project_name = ArizePhoenixLogger._get_dynamic_project_name(kwargs)
|
||||
if dynamic_project_name:
|
||||
safe_set_attribute(span, "openinference.project.name", dynamic_project_name)
|
||||
else:
|
||||
# Fall back to static config from env var
|
||||
config = ArizePhoenixLogger.get_arize_phoenix_config()
|
||||
if config.project_name:
|
||||
safe_set_attribute(span, "openinference.project.name", config.project_name)
|
||||
|
||||
return
|
||||
|
||||
@staticmethod
|
||||
def _get_dynamic_project_name(kwargs) -> Optional[str]:
|
||||
"""
|
||||
Retrieve dynamic Phoenix project name from request metadata.
|
||||
|
||||
Users can set `metadata.phoenix_project_name` in their request to route
|
||||
traces to different Phoenix projects dynamically.
|
||||
"""
|
||||
standard_logging_payload = kwargs.get("standard_logging_object")
|
||||
if isinstance(standard_logging_payload, dict):
|
||||
metadata = standard_logging_payload.get("metadata")
|
||||
if isinstance(metadata, dict):
|
||||
project_name = metadata.get("phoenix_project_name")
|
||||
if project_name:
|
||||
return str(project_name)
|
||||
|
||||
# Also check litellm_params.metadata for SDK usage
|
||||
litellm_params = kwargs.get("litellm_params")
|
||||
if isinstance(litellm_params, dict):
|
||||
metadata = litellm_params.get("metadata") or {}
|
||||
else:
|
||||
metadata = {}
|
||||
if isinstance(metadata, dict):
|
||||
project_name = metadata.get("phoenix_project_name")
|
||||
if project_name:
|
||||
return str(project_name)
|
||||
|
||||
return None
|
||||
|
||||
def _handle_success(self, kwargs, response_obj, start_time, end_time):
|
||||
"""
|
||||
Override to prevent creating duplicate litellm_request spans when a proxy parent span exists.
|
||||
|
||||
ArizePhoenixLogger should reuse the proxy parent span instead of creating a new litellm_request span,
|
||||
to maintain a shallow span hierarchy as expected by Arize Phoenix.
|
||||
"""
|
||||
from opentelemetry.trace import Status, StatusCode
|
||||
from litellm.secret_managers.main import get_secret_bool
|
||||
from litellm.integrations.opentelemetry import LITELLM_PROXY_REQUEST_SPAN_NAME
|
||||
|
||||
verbose_logger.debug(
|
||||
"ArizePhoenixLogger: Logging kwargs: %s, OTEL config settings=%s",
|
||||
kwargs,
|
||||
self.config,
|
||||
)
|
||||
ctx, parent_span = self._get_span_context(kwargs)
|
||||
|
||||
# ArizePhoenixLogger NEVER creates a litellm_request span when a proxy parent span exists
|
||||
# This is different from the base OpenTelemetry behavior which respects USE_OTEL_LITELLM_REQUEST_SPAN
|
||||
should_create_primary_span = parent_span is None or (
|
||||
parent_span.name != LITELLM_PROXY_REQUEST_SPAN_NAME
|
||||
and get_secret_bool("USE_OTEL_LITELLM_REQUEST_SPAN")
|
||||
)
|
||||
|
||||
if should_create_primary_span:
|
||||
# Create a new litellm_request span
|
||||
span = self._start_primary_span(
|
||||
kwargs, response_obj, start_time, end_time, ctx
|
||||
)
|
||||
# Raw-request sub-span (if enabled) - child of litellm_request span
|
||||
self._maybe_log_raw_request(
|
||||
kwargs, response_obj, start_time, end_time, span
|
||||
)
|
||||
# Ensure proxy-request parent span is annotated with the actual operation kind
|
||||
if (
|
||||
parent_span is not None
|
||||
and parent_span.name == LITELLM_PROXY_REQUEST_SPAN_NAME
|
||||
):
|
||||
self.set_attributes(parent_span, kwargs, response_obj)
|
||||
else:
|
||||
# Do not create primary span (keep hierarchy shallow when parent exists)
|
||||
span = None
|
||||
# Only set attributes if the span is still recording (not closed)
|
||||
# Note: parent_span is guaranteed to be not None here
|
||||
if parent_span.is_recording():
|
||||
parent_span.set_status(Status(StatusCode.OK))
|
||||
self.set_attributes(parent_span, kwargs, response_obj)
|
||||
# Raw-request as direct child of parent_span
|
||||
self._maybe_log_raw_request(
|
||||
kwargs, response_obj, start_time, end_time, parent_span
|
||||
)
|
||||
|
||||
# 3. Guardrail span
|
||||
self._create_guardrail_span(kwargs=kwargs, context=ctx)
|
||||
|
||||
# 4. Metrics & cost recording
|
||||
self._record_metrics(kwargs, response_obj, start_time, end_time)
|
||||
|
||||
# 5. Semantic logs.
|
||||
if self.config.enable_events:
|
||||
log_span = span if span is not None else parent_span
|
||||
if log_span is not None:
|
||||
self._emit_semantic_logs(kwargs, response_obj, log_span)
|
||||
|
||||
# 6. Do NOT end parent span - it should be managed by its creator
|
||||
# External spans (from Langfuse, user code, HTTP headers, global context) must not be closed by LiteLLM
|
||||
# However, proxy-created spans should be closed here
|
||||
if (
|
||||
parent_span is not None
|
||||
and parent_span.name == LITELLM_PROXY_REQUEST_SPAN_NAME
|
||||
):
|
||||
parent_span.end(end_time=self._to_ns(end_time))
|
||||
|
||||
@staticmethod
|
||||
def get_arize_phoenix_config() -> ArizePhoenixConfig:
|
||||
"""
|
||||
|
|
|
|||
|
|
@ -103,10 +103,15 @@ class CBFTransformer:
|
|||
# Use team_alias if available, otherwise team_id, otherwise fallback to 'unknown'
|
||||
entity_id = str(team_alias) if team_alias else (str(team_id) if team_id else 'unknown')
|
||||
|
||||
# Get alias fields if they exist
|
||||
api_key_alias = row.get('api_key_alias')
|
||||
organization_alias = row.get('organization_alias')
|
||||
project_alias = row.get('project_alias')
|
||||
user_alias = row.get('user_alias')
|
||||
|
||||
dimensions = {
|
||||
'entity_type': CZEntityType.TEAM.value,
|
||||
'entity_id': entity_id,
|
||||
'team_id': str(team_id) if team_id else 'unknown',
|
||||
'team_alias': str(team_alias) if team_alias else 'unknown',
|
||||
'model': model,
|
||||
'model_group': str(row.get('model_group', '')),
|
||||
|
|
@ -119,28 +124,37 @@ class CBFTransformer:
|
|||
'failed_requests': str(row.get('failed_requests', 0)),
|
||||
'cache_creation_tokens': str(row.get('cache_creation_input_tokens', 0)),
|
||||
'cache_read_tokens': str(row.get('cache_read_input_tokens', 0)),
|
||||
'organization_alias': str(organization_alias) if organization_alias else '',
|
||||
'project_alias': str(project_alias) if project_alias else '',
|
||||
'user_alias': str(user_alias) if user_alias else '',
|
||||
}
|
||||
|
||||
# Extract CZRN components to populate corresponding CBF columns
|
||||
czrn_components = self.czrn_generator.extract_components(resource_id)
|
||||
service_type, provider, region, owner_account_id, resource_type, cloud_local_id = czrn_components
|
||||
|
||||
# Build resource/account as concat of api_key_alias and api_key_prefix
|
||||
resource_account = f"{api_key_alias}|{api_key_hash}" if api_key_alias else api_key_hash
|
||||
|
||||
# CloudZero CBF format with proper column names
|
||||
cbf_record = {
|
||||
# Required CBF fields
|
||||
'time/usage_start': usage_date.isoformat() if usage_date else None, # Required: ISO-formatted UTC datetime
|
||||
'cost/cost': float(row.get('spend', 0.0)), # Required: billed cost
|
||||
'resource/id': resource_id, # Required when resource tags are present
|
||||
'resource/id': resource_id, # CZRN (CloudZero Resource Name)
|
||||
|
||||
# Usage metrics for token consumption
|
||||
'usage/amount': total_tokens, # Numeric value of tokens consumed
|
||||
'usage/units': 'tokens', # Description of token units
|
||||
|
||||
# CBF fields that correspond to CZRN components
|
||||
'resource/service': service_type, # Maps to CZRN service-type (litellm)
|
||||
'resource/account': owner_account_id, # Maps to CZRN owner-account-id (entity_id)
|
||||
# CBF fields - updated per LIT-1907
|
||||
'resource/service': str(row.get('model_group', '')), # Send model_group
|
||||
'resource/account': resource_account, # Send api_key_alias|api_key_prefix
|
||||
'resource/region': region, # Maps to CZRN region (cross-region)
|
||||
'resource/usage_family': resource_type, # Maps to CZRN resource-type (llm-usage)
|
||||
'resource/usage_family': str(row.get('custom_llm_provider', '')), # Send provider
|
||||
|
||||
# Action field
|
||||
'action/operation': str(team_id) if team_id else '', # Send team_id
|
||||
|
||||
# Line item details
|
||||
'lineitem/type': 'Usage', # Standard usage line item
|
||||
|
|
@ -155,13 +169,11 @@ class CBFTransformer:
|
|||
if value and value != 'N/A' and value != 'unknown': # Only add meaningful tags
|
||||
cbf_record[f'resource/tag:{key}'] = str(value)
|
||||
|
||||
# Add token breakdown as resource tags for analysis
|
||||
# Add token breakdown as resource tags for analysis (excluding total_tokens per LIT-1907)
|
||||
if prompt_tokens > 0:
|
||||
cbf_record['resource/tag:prompt_tokens'] = str(prompt_tokens)
|
||||
if completion_tokens > 0:
|
||||
cbf_record['resource/tag:completion_tokens'] = str(completion_tokens)
|
||||
if total_tokens > 0:
|
||||
cbf_record['resource/tag:total_tokens'] = str(total_tokens)
|
||||
|
||||
return CBFRecord(cbf_record)
|
||||
|
||||
|
|
|
|||
|
|
@ -30,6 +30,11 @@ from litellm.types.utils import (
|
|||
StandardLoggingGuardrailInformation,
|
||||
)
|
||||
|
||||
try:
|
||||
from fastapi.exceptions import HTTPException
|
||||
except ImportError:
|
||||
HTTPException = None # type: ignore
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from litellm.litellm_core_utils.litellm_logging import Logging as LiteLLMLoggingObj
|
||||
dc = DualCache()
|
||||
|
|
@ -624,7 +629,9 @@ class CustomGuardrail(CustomLogger):
|
|||
This gets logged on downsteam Langfuse, DataDog, etc.
|
||||
"""
|
||||
# Convert None to empty dict to satisfy type requirements
|
||||
guardrail_response = {} if response is None else response
|
||||
guardrail_response: Union[Dict[str, Any], str] = (
|
||||
{} if response is None else response
|
||||
)
|
||||
|
||||
# For apply_guardrail functions in custom_code_guardrail scenario,
|
||||
# simplify the logged response to "allow", "deny", or "mask"
|
||||
|
|
@ -648,6 +655,27 @@ class CustomGuardrail(CustomLogger):
|
|||
)
|
||||
return response
|
||||
|
||||
@staticmethod
|
||||
def _is_guardrail_intervention(e: Exception) -> bool:
|
||||
"""
|
||||
Returns True if the exception represents an intentional guardrail block
|
||||
(this was logged previously as an API failure - guardrail_failed_to_respond).
|
||||
|
||||
Guardrails signal intentional blocks by raising:
|
||||
- HTTPException with status 400 (content policy violation)
|
||||
- ModifyResponseException (passthrough mode violation)
|
||||
"""
|
||||
|
||||
if isinstance(e, ModifyResponseException):
|
||||
return True
|
||||
if (
|
||||
HTTPException is not None
|
||||
and isinstance(e, HTTPException)
|
||||
and e.status_code == 400
|
||||
):
|
||||
return True
|
||||
return False
|
||||
|
||||
def _process_error(
|
||||
self,
|
||||
e: Exception,
|
||||
|
|
@ -662,6 +690,11 @@ class CustomGuardrail(CustomLogger):
|
|||
|
||||
This gets logged on downsteam Langfuse, DataDog, etc.
|
||||
"""
|
||||
guardrail_status: GuardrailStatus = (
|
||||
"guardrail_intervened"
|
||||
if self._is_guardrail_intervention(e)
|
||||
else "guardrail_failed_to_respond"
|
||||
)
|
||||
# For custom_code_guardrail scenario, log as "deny" instead of full exception
|
||||
# Check if this is from custom_code_guardrail by checking the class name
|
||||
guardrail_response: Union[Exception, str] = e
|
||||
|
|
@ -671,7 +704,7 @@ class CustomGuardrail(CustomLogger):
|
|||
self.add_standard_logging_guardrail_information_to_request_data(
|
||||
guardrail_json_response=guardrail_response,
|
||||
request_data=request_data,
|
||||
guardrail_status="guardrail_failed_to_respond",
|
||||
guardrail_status=guardrail_status,
|
||||
duration=duration,
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
|
|
|
|||
|
|
@ -774,15 +774,17 @@ class CustomLogger: # https://docs.litellm.ai/docs/observability/custom_callbac
|
|||
self, model_call_details: Dict
|
||||
) -> Dict:
|
||||
"""
|
||||
Only redacts messages and responses when self.turn_off_message_logging is True
|
||||
Redacts or excludes fields from StandardLoggingPayload before callbacks receive it.
|
||||
|
||||
This method handles two features:
|
||||
1. turn_off_message_logging: When True, redacts messages and responses
|
||||
2. standard_logging_payload_excluded_fields: Removes specified fields entirely
|
||||
|
||||
By default, self.turn_off_message_logging is False and this does nothing.
|
||||
|
||||
Return a redacted deepcopy of the provided logging payload.
|
||||
Return a modified copy of the provided logging payload.
|
||||
|
||||
This is useful for logging payloads that contain sensitive information.
|
||||
"""
|
||||
import litellm
|
||||
from copy import copy
|
||||
|
||||
from litellm import Choices, Message, ModelResponse
|
||||
|
|
@ -790,14 +792,17 @@ class CustomLogger: # https://docs.litellm.ai/docs/observability/custom_callbac
|
|||
turn_off_message_logging: bool = getattr(
|
||||
self, "turn_off_message_logging", False
|
||||
)
|
||||
excluded_fields: Optional[List[str]] = getattr(
|
||||
litellm, "standard_logging_payload_excluded_fields", None
|
||||
)
|
||||
|
||||
if turn_off_message_logging is False:
|
||||
# Early return if no processing needed
|
||||
if turn_off_message_logging is False and not excluded_fields:
|
||||
return model_call_details
|
||||
|
||||
# Only make a shallow copy of the top-level dict to avoid deepcopy issues
|
||||
# with complex objects like AuthenticationError that may be present
|
||||
model_call_details_copy = copy(model_call_details)
|
||||
redacted_str = "redacted-by-litellm"
|
||||
standard_logging_object = model_call_details.get("standard_logging_object")
|
||||
if standard_logging_object is None:
|
||||
return model_call_details_copy
|
||||
|
|
@ -805,39 +810,58 @@ class CustomLogger: # https://docs.litellm.ai/docs/observability/custom_callbac
|
|||
# Make a copy of just the standard_logging_object to avoid modifying the original
|
||||
standard_logging_object_copy = copy(standard_logging_object)
|
||||
|
||||
if standard_logging_object_copy.get("messages") is not None:
|
||||
standard_logging_object_copy["messages"] = [
|
||||
Message(content=redacted_str).model_dump()
|
||||
]
|
||||
# Handle excluded fields - remove them entirely from the payload
|
||||
if excluded_fields:
|
||||
for field in excluded_fields:
|
||||
if field in standard_logging_object_copy:
|
||||
del standard_logging_object_copy[field]
|
||||
|
||||
if standard_logging_object_copy.get("response") is not None:
|
||||
response = standard_logging_object_copy["response"]
|
||||
# Check if this is a ResponsesAPIResponse (has "output" field)
|
||||
if isinstance(response, dict) and "output" in response:
|
||||
# Make a copy to avoid modifying the original
|
||||
from copy import deepcopy
|
||||
# Handle turn_off_message_logging - redact messages and responses (if not already excluded)
|
||||
if turn_off_message_logging:
|
||||
redacted_str = "redacted-by-litellm"
|
||||
|
||||
response_copy = deepcopy(response)
|
||||
# Redact content in output array
|
||||
if isinstance(response_copy.get("output"), list):
|
||||
for output_item in response_copy["output"]:
|
||||
if isinstance(output_item, dict) and "content" in output_item:
|
||||
if isinstance(output_item["content"], list):
|
||||
# Redact text in content items
|
||||
for content_item in output_item["content"]:
|
||||
if (
|
||||
isinstance(content_item, dict)
|
||||
and "text" in content_item
|
||||
):
|
||||
content_item["text"] = redacted_str
|
||||
standard_logging_object_copy["response"] = response_copy
|
||||
else:
|
||||
# Standard ModelResponse format
|
||||
model_response = ModelResponse(
|
||||
choices=[Choices(message=Message(content=redacted_str))]
|
||||
)
|
||||
model_response_dict = model_response.model_dump()
|
||||
standard_logging_object_copy["response"] = model_response_dict
|
||||
if (
|
||||
"messages" not in (excluded_fields or [])
|
||||
and standard_logging_object_copy.get("messages") is not None
|
||||
):
|
||||
standard_logging_object_copy["messages"] = [
|
||||
Message(content=redacted_str).model_dump()
|
||||
]
|
||||
|
||||
if (
|
||||
"response" not in (excluded_fields or [])
|
||||
and standard_logging_object_copy.get("response") is not None
|
||||
):
|
||||
response = standard_logging_object_copy["response"]
|
||||
# Check if this is a ResponsesAPIResponse (has "output" field)
|
||||
if isinstance(response, dict) and "output" in response:
|
||||
# Make a copy to avoid modifying the original
|
||||
from copy import deepcopy
|
||||
|
||||
response_copy = deepcopy(response)
|
||||
# Redact content in output array
|
||||
if isinstance(response_copy.get("output"), list):
|
||||
for output_item in response_copy["output"]:
|
||||
if (
|
||||
isinstance(output_item, dict)
|
||||
and "content" in output_item
|
||||
):
|
||||
if isinstance(output_item["content"], list):
|
||||
# Redact text in content items
|
||||
for content_item in output_item["content"]:
|
||||
if (
|
||||
isinstance(content_item, dict)
|
||||
and "text" in content_item
|
||||
):
|
||||
content_item["text"] = redacted_str
|
||||
standard_logging_object_copy["response"] = response_copy
|
||||
else:
|
||||
# Standard ModelResponse format
|
||||
model_response = ModelResponse(
|
||||
choices=[Choices(message=Message(content=redacted_str))]
|
||||
)
|
||||
model_response_dict = model_response.model_dump()
|
||||
standard_logging_object_copy["response"] = model_response_dict
|
||||
|
||||
model_call_details_copy["standard_logging_object"] = (
|
||||
standard_logging_object_copy
|
||||
|
|
|
|||
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue