Merge remote-tracking branch 'upstream/main' into oidc-bedrock-httpx-caching-part-1
 David Manouchehri
|
|
@ -44,6 +44,9 @@ jobs:
|
|||
pip install "logfire==0.29.0"
|
||||
pip install numpydoc
|
||||
pip install traceloop-sdk==0.21.1
|
||||
pip install opentelemetry-api==1.25.0
|
||||
pip install opentelemetry-sdk==1.25.0
|
||||
pip install opentelemetry-exporter-otlp==1.25.0
|
||||
pip install openai
|
||||
pip install prisma
|
||||
pip install "httpx==0.24.1"
|
||||
|
|
@ -341,4 +344,4 @@ workflows:
|
|||
filters:
|
||||
branches:
|
||||
only:
|
||||
- main
|
||||
- main
|
||||
34
.github/workflows/main.yml
vendored
Normal file
|
|
@ -0,0 +1,34 @@
|
|||
name: Publish Dev Release to PyPI
|
||||
|
||||
on:
|
||||
workflow_dispatch:
|
||||
|
||||
jobs:
|
||||
publish-dev-release:
|
||||
runs-on: ubuntu-latest
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v2
|
||||
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@v2
|
||||
with:
|
||||
python-version: 3.8 # Adjust the Python version as needed
|
||||
|
||||
- name: Install dependencies
|
||||
run: pip install toml twine
|
||||
|
||||
- name: Read version from pyproject.toml
|
||||
id: read-version
|
||||
run: |
|
||||
version=$(python -c 'import toml; print(toml.load("pyproject.toml")["tool"]["commitizen"]["version"])')
|
||||
printf "LITELLM_VERSION=%s" "$version" >> $GITHUB_ENV
|
||||
|
||||
- name: Check if version exists on PyPI
|
||||
id: check-version
|
||||
run: |
|
||||
set -e
|
||||
if twine check --repository-url https://pypi.org/simple/ "litellm==$LITELLM_VERSION" >/dev/null 2>&1; then
|
||||
echo "Version $LITELLM_VERSION already exists on PyPI. Skipping publish."
|
||||
|
||||
6
.gitignore
vendored
|
|
@ -55,4 +55,8 @@ litellm/proxy/_super_secret_config.yaml
|
|||
litellm/proxy/_super_secret_config.yaml
|
||||
litellm/proxy/myenv/bin/activate
|
||||
litellm/proxy/myenv/bin/Activate.ps1
|
||||
myenv/*
|
||||
myenv/*
|
||||
litellm/proxy/_experimental/out/404/index.html
|
||||
litellm/proxy/_experimental/out/model_hub/index.html
|
||||
litellm/proxy/_experimental/out/onboarding/index.html
|
||||
litellm/tests/log.txt
|
||||
|
|
|
|||
81
README.md
|
|
@ -147,6 +147,7 @@ The proxy provides:
|
|||
|
||||
## 📖 Proxy Endpoints - [Swagger Docs](https://litellm-api.up.railway.app/)
|
||||
|
||||
|
||||
## Quick Start Proxy - CLI
|
||||
|
||||
```shell
|
||||
|
|
@ -179,6 +180,24 @@ print(response)
|
|||
|
||||
## Proxy Key Management ([Docs](https://docs.litellm.ai/docs/proxy/virtual_keys))
|
||||
|
||||
Connect the proxy with a Postgres DB to create proxy keys
|
||||
|
||||
```bash
|
||||
# Get the code
|
||||
git clone https://github.com/BerriAI/litellm
|
||||
|
||||
# Go to folder
|
||||
cd litellm
|
||||
|
||||
# Add the master key
|
||||
echo 'LITELLM_MASTER_KEY="sk-1234"' > .env
|
||||
source .env
|
||||
|
||||
# Start
|
||||
docker-compose up
|
||||
```
|
||||
|
||||
|
||||
UI on `/ui` on your proxy server
|
||||
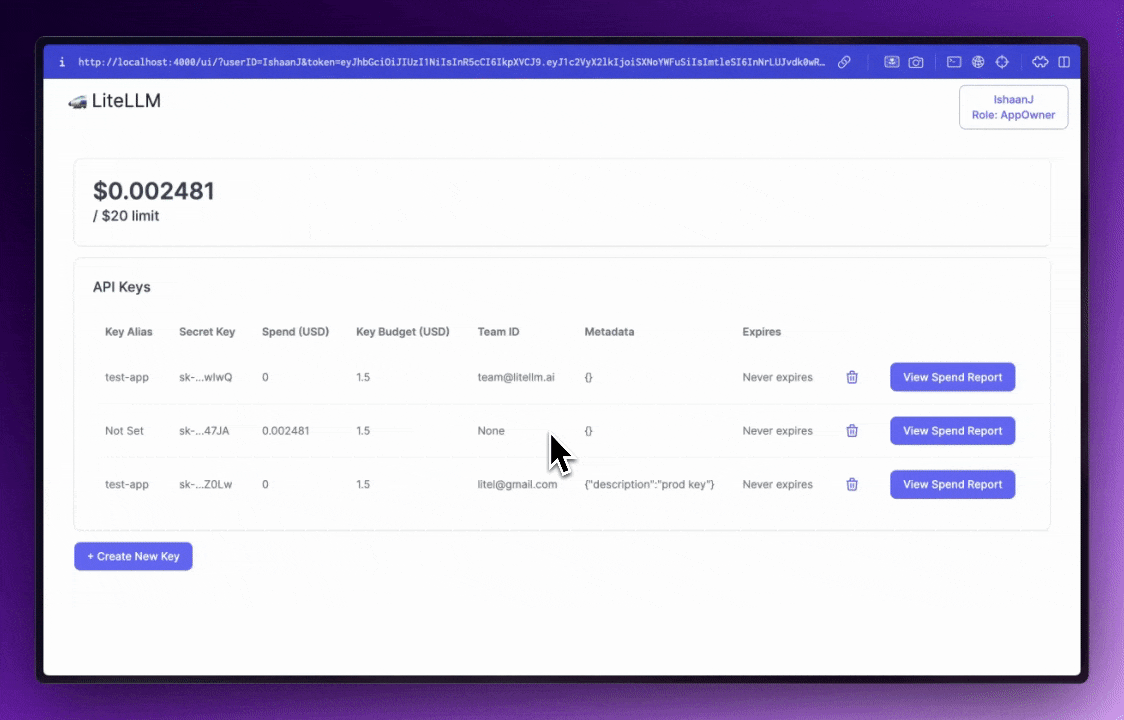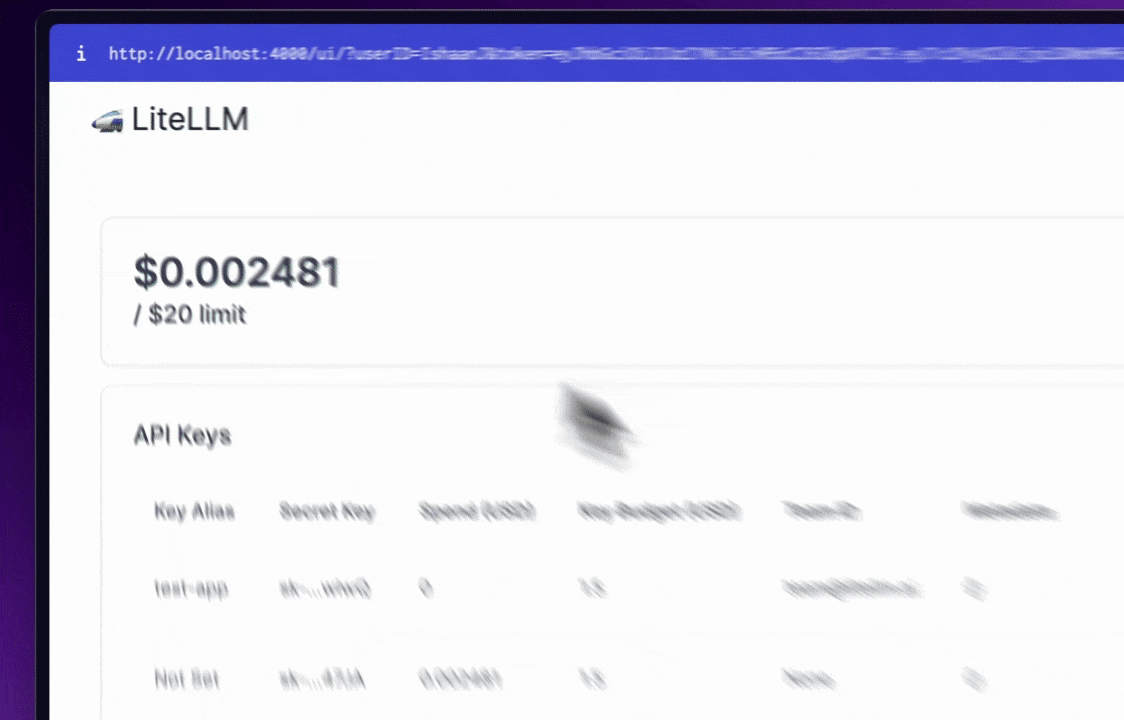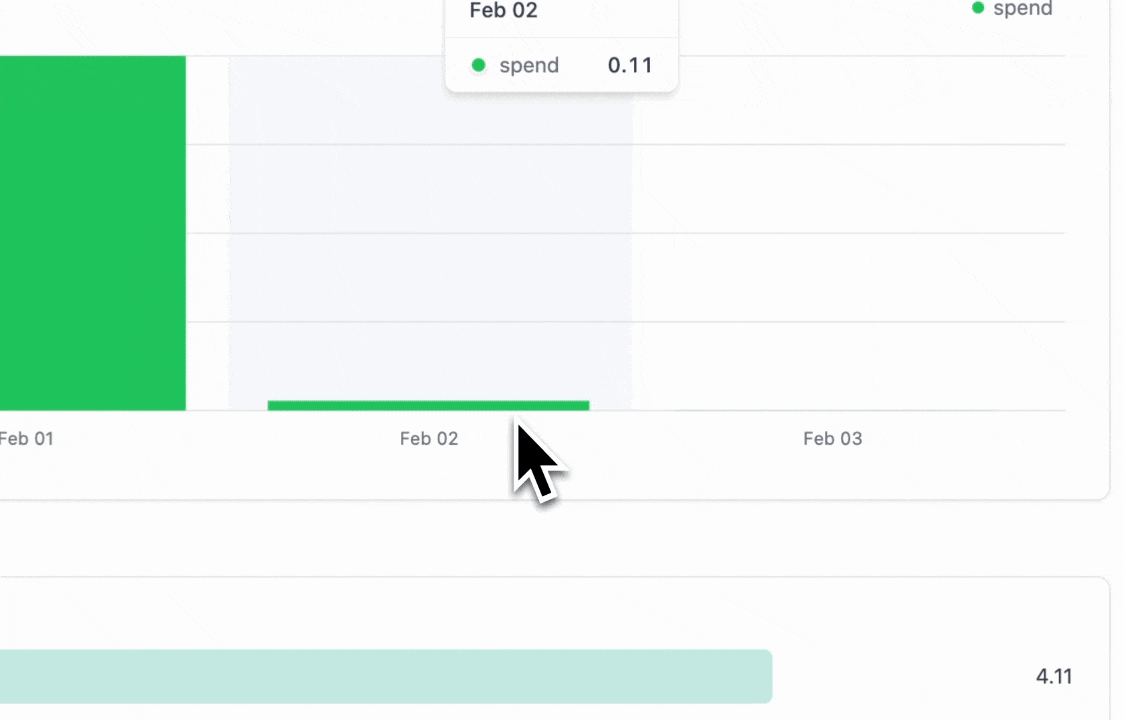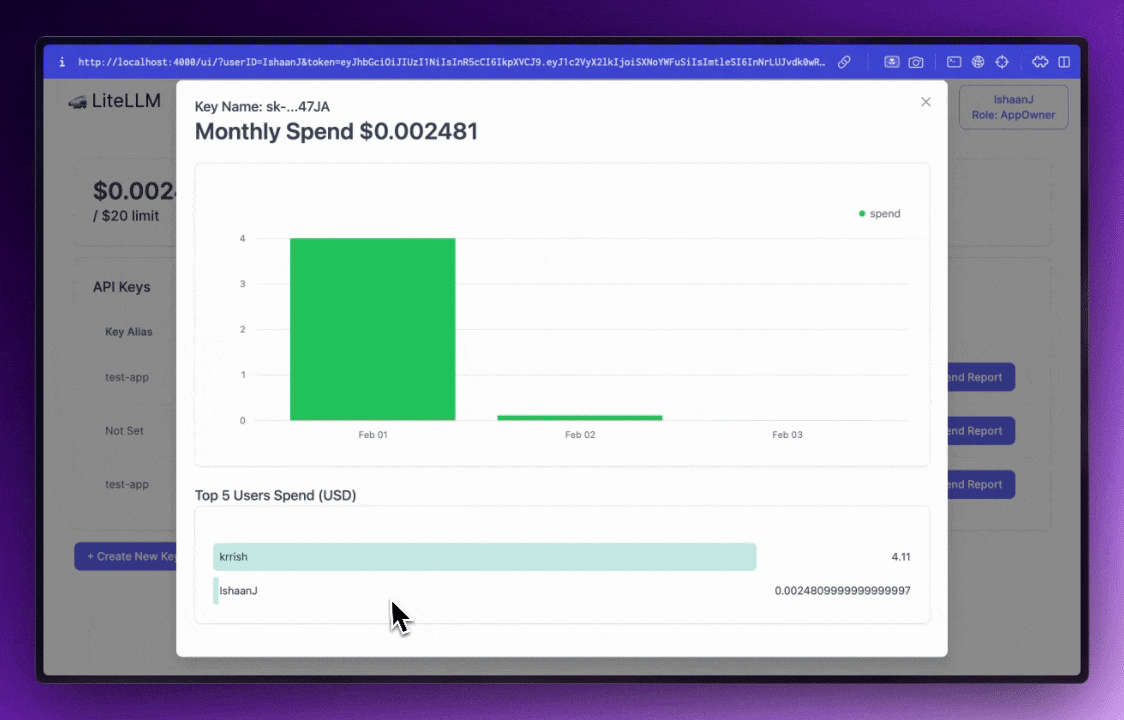
|
||||
|
||||
|
|
@ -206,37 +225,37 @@ curl 'http://0.0.0.0:4000/key/generate' \
|
|||
## Supported Providers ([Docs](https://docs.litellm.ai/docs/providers))
|
||||
|
||||
| Provider | [Completion](https://docs.litellm.ai/docs/#basic-usage) | [Streaming](https://docs.litellm.ai/docs/completion/stream#streaming-responses) | [Async Completion](https://docs.litellm.ai/docs/completion/stream#async-completion) | [Async Streaming](https://docs.litellm.ai/docs/completion/stream#async-streaming) | [Async Embedding](https://docs.litellm.ai/docs/embedding/supported_embedding) | [Async Image Generation](https://docs.litellm.ai/docs/image_generation) |
|
||||
| ----------------------------------------------------------------------------------- | ------------------------------------------------------- | ------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------- | --------------------------------------------------------------------------------- | ----------------------------------------------------------------------------- | ----------------------------------------------------------------------- |
|
||||
| [openai](https://docs.litellm.ai/docs/providers/openai) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| [azure](https://docs.litellm.ai/docs/providers/azure) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| [aws - sagemaker](https://docs.litellm.ai/docs/providers/aws_sagemaker) | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| [aws - bedrock](https://docs.litellm.ai/docs/providers/bedrock) | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| [google - vertex_ai [Gemini]](https://docs.litellm.ai/docs/providers/vertex) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [google - palm](https://docs.litellm.ai/docs/providers/palm) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [google AI Studio - gemini](https://docs.litellm.ai/docs/providers/gemini) | ✅ | ✅ | ✅ | ✅ | |
|
||||
| [mistral ai api](https://docs.litellm.ai/docs/providers/mistral) | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| [cloudflare AI Workers](https://docs.litellm.ai/docs/providers/cloudflare_workers) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [cohere](https://docs.litellm.ai/docs/providers/cohere) | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| [anthropic](https://docs.litellm.ai/docs/providers/anthropic) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [huggingface](https://docs.litellm.ai/docs/providers/huggingface) | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| [replicate](https://docs.litellm.ai/docs/providers/replicate) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [together_ai](https://docs.litellm.ai/docs/providers/togetherai) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [openrouter](https://docs.litellm.ai/docs/providers/openrouter) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [ai21](https://docs.litellm.ai/docs/providers/ai21) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [baseten](https://docs.litellm.ai/docs/providers/baseten) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [vllm](https://docs.litellm.ai/docs/providers/vllm) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [nlp_cloud](https://docs.litellm.ai/docs/providers/nlp_cloud) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [aleph alpha](https://docs.litellm.ai/docs/providers/aleph_alpha) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [petals](https://docs.litellm.ai/docs/providers/petals) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [ollama](https://docs.litellm.ai/docs/providers/ollama) | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| [deepinfra](https://docs.litellm.ai/docs/providers/deepinfra) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [perplexity-ai](https://docs.litellm.ai/docs/providers/perplexity) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [Groq AI](https://docs.litellm.ai/docs/providers/groq) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [Deepseek](https://docs.litellm.ai/docs/providers/deepseek) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [anyscale](https://docs.litellm.ai/docs/providers/anyscale) | ✅ | ✅ | ✅ | ✅ |
|
||||
| [IBM - watsonx.ai](https://docs.litellm.ai/docs/providers/watsonx) | ✅ | ✅ | ✅ | ✅ | ✅
|
||||
| [voyage ai](https://docs.litellm.ai/docs/providers/voyage) | | | | | ✅ |
|
||||
| [xinference [Xorbits Inference]](https://docs.litellm.ai/docs/providers/xinference) | | | | | ✅ |
|
||||
|-------------------------------------------------------------------------------------|---------------------------------------------------------|---------------------------------------------------------------------------------|-------------------------------------------------------------------------------------|-----------------------------------------------------------------------------------|-------------------------------------------------------------------------------|-------------------------------------------------------------------------|
|
||||
| [openai](https://docs.litellm.ai/docs/providers/openai) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| [azure](https://docs.litellm.ai/docs/providers/azure) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| [aws - sagemaker](https://docs.litellm.ai/docs/providers/aws_sagemaker) | ✅ | ✅ | ✅ | ✅ | ✅ | |
|
||||
| [aws - bedrock](https://docs.litellm.ai/docs/providers/bedrock) | ✅ | ✅ | ✅ | ✅ | ✅ | |
|
||||
| [google - vertex_ai](https://docs.litellm.ai/docs/providers/vertex) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| [google - palm](https://docs.litellm.ai/docs/providers/palm) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [google AI Studio - gemini](https://docs.litellm.ai/docs/providers/gemini) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [mistral ai api](https://docs.litellm.ai/docs/providers/mistral) | ✅ | ✅ | ✅ | ✅ | ✅ | |
|
||||
| [cloudflare AI Workers](https://docs.litellm.ai/docs/providers/cloudflare_workers) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [cohere](https://docs.litellm.ai/docs/providers/cohere) | ✅ | ✅ | ✅ | ✅ | ✅ | |
|
||||
| [anthropic](https://docs.litellm.ai/docs/providers/anthropic) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [huggingface](https://docs.litellm.ai/docs/providers/huggingface) | ✅ | ✅ | ✅ | ✅ | ✅ | |
|
||||
| [replicate](https://docs.litellm.ai/docs/providers/replicate) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [together_ai](https://docs.litellm.ai/docs/providers/togetherai) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [openrouter](https://docs.litellm.ai/docs/providers/openrouter) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [ai21](https://docs.litellm.ai/docs/providers/ai21) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [baseten](https://docs.litellm.ai/docs/providers/baseten) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [vllm](https://docs.litellm.ai/docs/providers/vllm) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [nlp_cloud](https://docs.litellm.ai/docs/providers/nlp_cloud) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [aleph alpha](https://docs.litellm.ai/docs/providers/aleph_alpha) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [petals](https://docs.litellm.ai/docs/providers/petals) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [ollama](https://docs.litellm.ai/docs/providers/ollama) | ✅ | ✅ | ✅ | ✅ | ✅ | |
|
||||
| [deepinfra](https://docs.litellm.ai/docs/providers/deepinfra) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [perplexity-ai](https://docs.litellm.ai/docs/providers/perplexity) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [Groq AI](https://docs.litellm.ai/docs/providers/groq) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [Deepseek](https://docs.litellm.ai/docs/providers/deepseek) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [anyscale](https://docs.litellm.ai/docs/providers/anyscale) | ✅ | ✅ | ✅ | ✅ | | |
|
||||
| [IBM - watsonx.ai](https://docs.litellm.ai/docs/providers/watsonx) | ✅ | ✅ | ✅ | ✅ | ✅ | |
|
||||
| [voyage ai](https://docs.litellm.ai/docs/providers/voyage) | | | | | ✅ | |
|
||||
| [xinference [Xorbits Inference]](https://docs.litellm.ai/docs/providers/xinference) | | | | | ✅ | |
|
||||
|
||||
[**Read the Docs**](https://docs.litellm.ai/docs/)
|
||||
|
||||
|
|
|
|||
|
|
@ -1,16 +1,29 @@
|
|||
version: "3.9"
|
||||
version: "3.11"
|
||||
services:
|
||||
litellm:
|
||||
build:
|
||||
context: .
|
||||
args:
|
||||
target: runtime
|
||||
image: ghcr.io/berriai/litellm:main-latest
|
||||
image: ghcr.io/berriai/litellm:main-stable
|
||||
ports:
|
||||
- "4000:4000" # Map the container port to the host, change the host port if necessary
|
||||
volumes:
|
||||
- ./litellm-config.yaml:/app/config.yaml # Mount the local configuration file
|
||||
# You can change the port or number of workers as per your requirements or pass any new supported CLI augument. Make sure the port passed here matches with the container port defined above in `ports` value
|
||||
command: [ "--config", "/app/config.yaml", "--port", "4000", "--num_workers", "8" ]
|
||||
environment:
|
||||
DATABASE_URL: "postgresql://postgres:example@db:5432/postgres"
|
||||
STORE_MODEL_IN_DB: "True" # allows adding models to proxy via UI
|
||||
env_file:
|
||||
- .env # Load local .env file
|
||||
|
||||
|
||||
db:
|
||||
image: postgres
|
||||
restart: always
|
||||
environment:
|
||||
POSTGRES_PASSWORD: example
|
||||
healthcheck:
|
||||
test: ["CMD-SHELL", "pg_isready"]
|
||||
interval: 1s
|
||||
timeout: 5s
|
||||
retries: 10
|
||||
|
||||
# ...rest of your docker-compose config if any
|
||||
238
docs/my-website/docs/assistants.md
Normal file
|
|
@ -0,0 +1,238 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Assistants API
|
||||
|
||||
Covers Threads, Messages, Assistants.
|
||||
|
||||
LiteLLM currently covers:
|
||||
- Get Assistants
|
||||
- Create Thread
|
||||
- Get Thread
|
||||
- Add Messages
|
||||
- Get Messages
|
||||
- Run Thread
|
||||
|
||||
## Quick Start
|
||||
|
||||
Call an existing Assistant.
|
||||
|
||||
- Get the Assistant
|
||||
|
||||
- Create a Thread when a user starts a conversation.
|
||||
|
||||
- Add Messages to the Thread as the user asks questions.
|
||||
|
||||
- Run the Assistant on the Thread to generate a response by calling the model and the tools.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
**Get the Assistant**
|
||||
|
||||
```python
|
||||
from litellm import get_assistants, aget_assistants
|
||||
import os
|
||||
|
||||
# setup env
|
||||
os.environ["OPENAI_API_KEY"] = "sk-.."
|
||||
|
||||
assistants = get_assistants(custom_llm_provider="openai")
|
||||
|
||||
### ASYNC USAGE ###
|
||||
# assistants = await aget_assistants(custom_llm_provider="openai")
|
||||
```
|
||||
|
||||
**Create a Thread**
|
||||
|
||||
```python
|
||||
from litellm import create_thread, acreate_thread
|
||||
import os
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "sk-.."
|
||||
|
||||
new_thread = create_thread(
|
||||
custom_llm_provider="openai",
|
||||
messages=[{"role": "user", "content": "Hey, how's it going?"}], # type: ignore
|
||||
)
|
||||
|
||||
### ASYNC USAGE ###
|
||||
# new_thread = await acreate_thread(custom_llm_provider="openai",messages=[{"role": "user", "content": "Hey, how's it going?"}])
|
||||
```
|
||||
|
||||
**Add Messages to the Thread**
|
||||
|
||||
```python
|
||||
from litellm import create_thread, get_thread, aget_thread, add_message, a_add_message
|
||||
import os
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "sk-.."
|
||||
|
||||
## CREATE A THREAD
|
||||
_new_thread = create_thread(
|
||||
custom_llm_provider="openai",
|
||||
messages=[{"role": "user", "content": "Hey, how's it going?"}], # type: ignore
|
||||
)
|
||||
|
||||
## OR retrieve existing thread
|
||||
received_thread = get_thread(
|
||||
custom_llm_provider="openai",
|
||||
thread_id=_new_thread.id,
|
||||
)
|
||||
|
||||
### ASYNC USAGE ###
|
||||
# received_thread = await aget_thread(custom_llm_provider="openai", thread_id=_new_thread.id,)
|
||||
|
||||
## ADD MESSAGE TO THREAD
|
||||
message = {"role": "user", "content": "Hey, how's it going?"}
|
||||
added_message = add_message(
|
||||
thread_id=_new_thread.id, custom_llm_provider="openai", **message
|
||||
)
|
||||
|
||||
### ASYNC USAGE ###
|
||||
# added_message = await a_add_message(thread_id=_new_thread.id, custom_llm_provider="openai", **message)
|
||||
```
|
||||
|
||||
**Run the Assistant on the Thread**
|
||||
|
||||
```python
|
||||
from litellm import get_assistants, create_thread, add_message, run_thread, arun_thread
|
||||
import os
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "sk-.."
|
||||
assistants = get_assistants(custom_llm_provider="openai")
|
||||
|
||||
## get the first assistant ###
|
||||
assistant_id = assistants.data[0].id
|
||||
|
||||
## GET A THREAD
|
||||
_new_thread = create_thread(
|
||||
custom_llm_provider="openai",
|
||||
messages=[{"role": "user", "content": "Hey, how's it going?"}], # type: ignore
|
||||
)
|
||||
|
||||
## ADD MESSAGE
|
||||
message = {"role": "user", "content": "Hey, how's it going?"}
|
||||
added_message = add_message(
|
||||
thread_id=_new_thread.id, custom_llm_provider="openai", **message
|
||||
)
|
||||
|
||||
## 🚨 RUN THREAD
|
||||
response = run_thread(
|
||||
custom_llm_provider="openai", thread_id=thread_id, assistant_id=assistant_id
|
||||
)
|
||||
|
||||
### ASYNC USAGE ###
|
||||
# response = await arun_thread(custom_llm_provider="openai", thread_id=thread_id, assistant_id=assistant_id)
|
||||
|
||||
print(f"run_thread: {run_thread}")
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
```yaml
|
||||
assistant_settings:
|
||||
custom_llm_provider: azure
|
||||
litellm_params:
|
||||
api_key: os.environ/AZURE_API_KEY
|
||||
api_base: os.environ/AZURE_API_BASE
|
||||
api_version: os.environ/AZURE_API_VERSION
|
||||
```
|
||||
|
||||
```bash
|
||||
$ litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
**Get the Assistant**
|
||||
|
||||
```bash
|
||||
curl "http://0.0.0.0:4000/v1/assistants?order=desc&limit=20" \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234"
|
||||
```
|
||||
|
||||
**Create a Thread**
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/threads \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d ''
|
||||
```
|
||||
|
||||
**Get a Thread**
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/threads/{thread_id} \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234"
|
||||
```
|
||||
|
||||
**Add Messages to the Thread**
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/threads/{thread_id}/messages \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"role": "user",
|
||||
"content": "How does AI work? Explain it in simple terms."
|
||||
}'
|
||||
```
|
||||
|
||||
**Run the Assistant on the Thread**
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/threads/thread_abc123/runs \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"assistant_id": "asst_abc123"
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Streaming
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
from litellm import run_thread_stream
|
||||
import os
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "sk-.."
|
||||
|
||||
message = {"role": "user", "content": "Hey, how's it going?"}
|
||||
|
||||
data = {"custom_llm_provider": "openai", "thread_id": _new_thread.id, "assistant_id": assistant_id, **message}
|
||||
|
||||
run = run_thread_stream(**data)
|
||||
with run as run:
|
||||
assert isinstance(run, AssistantEventHandler)
|
||||
for chunk in run:
|
||||
print(f"chunk: {chunk}")
|
||||
run.until_done()
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
```bash
|
||||
curl -X POST 'http://0.0.0.0:4000/threads/{thread_id}/runs' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-D '{
|
||||
"assistant_id": "asst_6xVZQFFy1Kw87NbnYeNebxTf",
|
||||
"stream": true
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## [👉 Proxy API Reference](https://litellm-api.up.railway.app/#/assistants)
|
||||
124
docs/my-website/docs/batches.md
Normal file
|
|
@ -0,0 +1,124 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Batches API
|
||||
|
||||
Covers Batches, Files
|
||||
|
||||
|
||||
## Quick Start
|
||||
|
||||
Call an existing Assistant.
|
||||
|
||||
- Create File for Batch Completion
|
||||
|
||||
- Create Batch Request
|
||||
|
||||
- Retrieve the Specific Batch and File Content
|
||||
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
**Create File for Batch Completion**
|
||||
|
||||
```python
|
||||
from litellm
|
||||
import os
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "sk-.."
|
||||
|
||||
file_name = "openai_batch_completions.jsonl"
|
||||
_current_dir = os.path.dirname(os.path.abspath(__file__))
|
||||
file_path = os.path.join(_current_dir, file_name)
|
||||
file_obj = await litellm.acreate_file(
|
||||
file=open(file_path, "rb"),
|
||||
purpose="batch",
|
||||
custom_llm_provider="openai",
|
||||
)
|
||||
print("Response from creating file=", file_obj)
|
||||
```
|
||||
|
||||
**Create Batch Request**
|
||||
|
||||
```python
|
||||
from litellm
|
||||
import os
|
||||
|
||||
create_batch_response = await litellm.acreate_batch(
|
||||
completion_window="24h",
|
||||
endpoint="/v1/chat/completions",
|
||||
input_file_id=batch_input_file_id,
|
||||
custom_llm_provider="openai",
|
||||
metadata={"key1": "value1", "key2": "value2"},
|
||||
)
|
||||
|
||||
print("response from litellm.create_batch=", create_batch_response)
|
||||
```
|
||||
|
||||
**Retrieve the Specific Batch and File Content**
|
||||
|
||||
```python
|
||||
|
||||
retrieved_batch = await litellm.aretrieve_batch(
|
||||
batch_id=create_batch_response.id, custom_llm_provider="openai"
|
||||
)
|
||||
print("retrieved batch=", retrieved_batch)
|
||||
# just assert that we retrieved a non None batch
|
||||
|
||||
assert retrieved_batch.id == create_batch_response.id
|
||||
|
||||
# try to get file content for our original file
|
||||
|
||||
file_content = await litellm.afile_content(
|
||||
file_id=batch_input_file_id, custom_llm_provider="openai"
|
||||
)
|
||||
|
||||
print("file content = ", file_content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
```bash
|
||||
$ export OPENAI_API_KEY="sk-..."
|
||||
|
||||
$ litellm
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
**Create File for Batch Completion**
|
||||
|
||||
```shell
|
||||
curl https://api.openai.com/v1/files \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-F purpose="batch" \
|
||||
-F file="@mydata.jsonl"
|
||||
```
|
||||
|
||||
**Create Batch Request**
|
||||
|
||||
```bash
|
||||
curl http://localhost:4000/v1/batches \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"input_file_id": "file-abc123",
|
||||
"endpoint": "/v1/chat/completions",
|
||||
"completion_window": "24h"
|
||||
}'
|
||||
```
|
||||
|
||||
**Retrieve the Specific Batch**
|
||||
|
||||
```bash
|
||||
curl http://localhost:4000/v1/batches/batch_abc123 \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## [👉 Proxy API Reference](https://litellm-api.up.railway.app/#/batch)
|
||||
|
|
@ -212,6 +212,94 @@ If you run the code two times, response1 will use the cache from the first run t
|
|||
|
||||
</TabItem>
|
||||
|
||||
</Tabs>
|
||||
|
||||
## Switch Cache On / Off Per LiteLLM Call
|
||||
|
||||
LiteLLM supports 4 cache-controls:
|
||||
|
||||
- `no-cache`: *Optional(bool)* When `True`, Will not return a cached response, but instead call the actual endpoint.
|
||||
- `no-store`: *Optional(bool)* When `True`, Will not cache the response.
|
||||
- `ttl`: *Optional(int)* - Will cache the response for the user-defined amount of time (in seconds).
|
||||
- `s-maxage`: *Optional(int)* Will only accept cached responses that are within user-defined range (in seconds).
|
||||
|
||||
[Let us know if you need more](https://github.com/BerriAI/litellm/issues/1218)
|
||||
<Tabs>
|
||||
<TabItem value="no-cache" label="No-Cache">
|
||||
|
||||
Example usage `no-cache` - When `True`, Will not return a cached response
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "hello who are you"
|
||||
}
|
||||
],
|
||||
cache={"no-cache": True},
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="no-store" label="No-Store">
|
||||
|
||||
Example usage `no-store` - When `True`, Will not cache the response.
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "hello who are you"
|
||||
}
|
||||
],
|
||||
cache={"no-store": True},
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="ttl" label="ttl">
|
||||
Example usage `ttl` - cache the response for 10 seconds
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "hello who are you"
|
||||
}
|
||||
],
|
||||
cache={"ttl": 10},
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="s-maxage" label="s-maxage">
|
||||
Example usage `s-maxage` - Will only accept cached responses for 60 seconds
|
||||
|
||||
```python
|
||||
response = litellm.completion(
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "hello who are you"
|
||||
}
|
||||
],
|
||||
cache={"s-maxage": 60},
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
|
||||
</Tabs>
|
||||
|
||||
## Cache Context Manager - Enable, Disable, Update Cache
|
||||
|
|
|
|||
|
|
@ -39,38 +39,34 @@ This is a list of openai params we translate across providers.
|
|||
|
||||
Use `litellm.get_supported_openai_params()` for an updated list of params for each model + provider
|
||||
|
||||
| Provider | temperature | max_tokens | top_p | stream | stop | n | presence_penalty | frequency_penalty | functions | function_call | logit_bias | user | response_format | seed | tools | tool_choice | logprobs | top_logprobs | extra_headers |
|
||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|--|
|
||||
|Anthropic| ✅ | ✅ | ✅ | ✅ | ✅ | | | | | | |✅ | ✅ | ✅ | ✅ | ✅ | | | ✅
|
||||
|OpenAI| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |✅ | ✅ | ✅ | ✅ |✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
|Azure OpenAI| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |✅ | ✅ | ✅ | ✅ |✅ | ✅ | | | ✅ |
|
||||
| Provider | temperature | max_tokens | top_p | stream | stream_options | stop | n | presence_penalty | frequency_penalty | functions | function_call | logit_bias | user | response_format | seed | tools | tool_choice | logprobs | top_logprobs | extra_headers |
|
||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
|
||||
|Anthropic| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | | | | | | |✅ | ✅ | ✅ | ✅ | ✅ | | | ✅ |
|
||||
|OpenAI| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |✅ | ✅ | ✅ | ✅ |✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
|Azure OpenAI| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |✅ | ✅ | ✅ | ✅ |✅ | ✅ | | | ✅ |
|
||||
|Replicate | ✅ | ✅ | ✅ | ✅ | ✅ | | | | | |
|
||||
|Anyscale | ✅ | ✅ | ✅ | ✅ |
|
||||
|Anyscale | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
|Cohere| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | | |
|
||||
|Huggingface| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | | | | |
|
||||
|Huggingface| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | | | |
|
||||
|Openrouter| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | | | | | ✅ | | | | |
|
||||
|AI21| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | | |
|
||||
|VertexAI| ✅ | ✅ | | ✅ | | | | | | | | | | | ✅ | | |
|
||||
|VertexAI| ✅ | ✅ | | ✅ | ✅ | | | | | | | | | | ✅ | | |
|
||||
|Bedrock| ✅ | ✅ | ✅ | ✅ | ✅ | | | | | | | | | | ✅ (for anthropic) | |
|
||||
|Sagemaker| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | | | | |
|
||||
|Sagemaker| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | | | |
|
||||
|TogetherAI| ✅ | ✅ | ✅ | ✅ | ✅ | | | | | | ✅ |
|
||||
|AlephAlpha| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | | | | |
|
||||
|Palm| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | | | | |
|
||||
|NLP Cloud| ✅ | ✅ | ✅ | ✅ | ✅ | | | | | |
|
||||
|Petals| ✅ | ✅ | | ✅ | | | | | | |
|
||||
|AlephAlpha| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | | | |
|
||||
|Palm| ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | | | |
|
||||
|NLP Cloud| ✅ | ✅ | ✅ | ✅ | ✅ | | | | | |
|
||||
|Petals| ✅ | ✅ | | ✅ | ✅ | | | | | |
|
||||
|Ollama| ✅ | ✅ | ✅ | ✅ | ✅ | | | ✅ | | | | | ✅ | | |
|
||||
|Databricks| ✅ | ✅ | ✅ | ✅ | ✅ | | | | | | | | | | |
|
||||
|ClarifAI| ✅ | ✅ | | | | | | | | | | | | | |
|
||||
|
||||
|ClarifAI| ✅ | ✅ | |✅ | ✅ | | | | | | | | | | |
|
||||
:::note
|
||||
|
||||
By default, LiteLLM raises an exception if the openai param being passed in isn't supported.
|
||||
|
||||
To drop the param instead, set `litellm.drop_params = True`.
|
||||
To drop the param instead, set `litellm.drop_params = True` or `completion(..drop_params=True)`.
|
||||
|
||||
**For function calling:**
|
||||
|
||||
Add to prompt for non-openai models, set: `litellm.add_function_to_prompt = True`.
|
||||
:::
|
||||
|
||||
## Input Params
|
||||
|
|
|
|||
|
|
@ -10,13 +10,17 @@ For companies that need SSO, user management and professional support for LiteLL
|
|||
This covers:
|
||||
- ✅ **Features under the [LiteLLM Commercial License (Content Mod, Custom Tags, etc.)](https://docs.litellm.ai/docs/proxy/enterprise)**
|
||||
- ✅ [**Secure UI access with Single Sign-On**](../docs/proxy/ui.md#setup-ssoauth-for-ui)
|
||||
- ✅ [**Audit Logs with retention policy**](../docs/proxy/enterprise.md#audit-logs)
|
||||
- ✅ [**JWT-Auth**](../docs/proxy/token_auth.md)
|
||||
- ✅ [**Prompt Injection Detection**](#prompt-injection-detection-lakeraai)
|
||||
- ✅ [**Invite Team Members to access `/spend` Routes**](../docs/proxy/cost_tracking#allowing-non-proxy-admins-to-access-spend-endpoints)
|
||||
- ✅ **Feature Prioritization**
|
||||
- ✅ **Custom Integrations**
|
||||
- ✅ **Professional Support - Dedicated discord + slack**
|
||||
- ✅ **Custom SLAs**
|
||||
- ✅ [**Custom Swagger**](../docs/proxy/enterprise.md#swagger-docs---custom-routes--branding)
|
||||
- ✅ [**Public Model Hub**](../docs/proxy/enterprise.md#public-model-hub)
|
||||
- ✅ [**Custom Email Branding**](../docs/proxy/email.md#customizing-email-branding)
|
||||
|
||||
|
||||
|
||||
## [COMING SOON] AWS Marketplace Support
|
||||
|
|
@ -33,7 +37,11 @@ Includes all enterprise features.
|
|||
|
||||
Professional Support can assist with LLM/Provider integrations, deployment, upgrade management, and LLM Provider troubleshooting. We can’t solve your own infrastructure-related issues but we will guide you to fix them.
|
||||
|
||||
We offer custom SLAs based on your needs and the severity of the issue. The standard SLA is 6 hours for Sev0-Sev1 severity and 24h for Sev2-Sev3 between 7am – 7pm PT (Monday through Saturday).
|
||||
- 1 hour for Sev0 issues
|
||||
- 6 hours for Sev1
|
||||
- 24h for Sev2-Sev3 between 7am – 7pm PT (Monday through Saturday)
|
||||
|
||||
**We can offer custom SLAs** based on your needs and the severity of the issue
|
||||
|
||||
### What’s the cost of the Self-Managed Enterprise edition?
|
||||
|
||||
|
|
|
|||
|
|
@ -51,7 +51,7 @@ print(f"response: {response}")
|
|||
|
||||
- `api_base`: *string (optional)* - The api endpoint you want to call the model with
|
||||
|
||||
- `api_version`: *string (optional)* - (Azure-specific) the api version for the call
|
||||
- `api_version`: *string (optional)* - (Azure-specific) the api version for the call; required for dall-e-3 on Azure
|
||||
|
||||
- `api_key`: *string (optional)* - The API key to authenticate and authorize requests. If not provided, the default API key is used.
|
||||
|
||||
|
|
@ -166,4 +166,4 @@ response = litellm.image_generation(
|
|||
vertex_ai_location="us-central1",
|
||||
)
|
||||
print(f"response: {response}")
|
||||
```
|
||||
```
|
||||
|
|
|
|||
|
|
@ -38,7 +38,7 @@ class MyCustomHandler(CustomLogger):
|
|||
print(f"On Async Success")
|
||||
|
||||
async def async_log_failure_event(self, kwargs, response_obj, start_time, end_time):
|
||||
print(f"On Async Success")
|
||||
print(f"On Async Failure")
|
||||
|
||||
customHandler = MyCustomHandler()
|
||||
|
||||
|
|
|
|||
|
|
@ -144,6 +144,26 @@ print(response)
|
|||
|
||||
```
|
||||
|
||||
You can also pass `metadata` as part of the request header with a `langfuse_*` prefix:
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'langfuse_trace_id: trace-id22' \
|
||||
--header 'langfuse_trace_user_id: user-id2' \
|
||||
--header 'langfuse_trace_metadata: {"key":"value"}' \
|
||||
--data '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
|
||||
### Trace & Generation Parameters
|
||||
|
||||
#### Trace Specific Parameters
|
||||
|
|
|
|||
5
docs/my-website/docs/projects/llm_cord.md
Normal file
|
|
@ -0,0 +1,5 @@
|
|||
# llmcord.py
|
||||
|
||||
llmcord.py lets you and your friends chat with LLMs directly in your Discord server. It works with practically any LLM, remote or locally hosted.
|
||||
|
||||
Github: https://github.com/jakobdylanc/discord-llm-chatbot
|
||||
|
|
@ -361,47 +361,6 @@ response = completion(
|
|||
)
|
||||
```
|
||||
|
||||
### Passing an external BedrockRuntime.Client as a parameter - Completion()
|
||||
Pass an external BedrockRuntime.Client object as a parameter to litellm.completion. Useful when using an AWS credentials profile, SSO session, assumed role session, or if environment variables are not available for auth.
|
||||
|
||||
Create a client from session credentials:
|
||||
```python
|
||||
import boto3
|
||||
from litellm import completion
|
||||
|
||||
bedrock = boto3.client(
|
||||
service_name="bedrock-runtime",
|
||||
region_name="us-east-1",
|
||||
aws_access_key_id="",
|
||||
aws_secret_access_key="",
|
||||
aws_session_token="",
|
||||
)
|
||||
|
||||
response = completion(
|
||||
model="bedrock/anthropic.claude-instant-v1",
|
||||
messages=[{ "content": "Hello, how are you?","role": "user"}],
|
||||
aws_bedrock_client=bedrock,
|
||||
)
|
||||
```
|
||||
|
||||
Create a client from AWS profile in `~/.aws/config`:
|
||||
```python
|
||||
import boto3
|
||||
from litellm import completion
|
||||
|
||||
dev_session = boto3.Session(profile_name="dev-profile")
|
||||
bedrock = dev_session.client(
|
||||
service_name="bedrock-runtime",
|
||||
region_name="us-east-1",
|
||||
)
|
||||
|
||||
response = completion(
|
||||
model="bedrock/anthropic.claude-instant-v1",
|
||||
messages=[{ "content": "Hello, how are you?","role": "user"}],
|
||||
aws_bedrock_client=bedrock,
|
||||
)
|
||||
```
|
||||
|
||||
### SSO Login (AWS Profile)
|
||||
- Set `AWS_PROFILE` environment variable
|
||||
- Make bedrock completion call
|
||||
|
|
@ -464,6 +423,56 @@ response = completion(
|
|||
)
|
||||
```
|
||||
|
||||
|
||||
### Passing an external BedrockRuntime.Client as a parameter - Completion()
|
||||
|
||||
:::warning
|
||||
|
||||
This is a deprecated flow. Boto3 is not async. And boto3.client does not let us make the http call through httpx. Pass in your aws params through the method above 👆. [See Auth Code](https://github.com/BerriAI/litellm/blob/55a20c7cce99a93d36a82bf3ae90ba3baf9a7f89/litellm/llms/bedrock_httpx.py#L284) [Add new auth flow](https://github.com/BerriAI/litellm/issues)
|
||||
|
||||
:::
|
||||
|
||||
Pass an external BedrockRuntime.Client object as a parameter to litellm.completion. Useful when using an AWS credentials profile, SSO session, assumed role session, or if environment variables are not available for auth.
|
||||
|
||||
Create a client from session credentials:
|
||||
```python
|
||||
import boto3
|
||||
from litellm import completion
|
||||
|
||||
bedrock = boto3.client(
|
||||
service_name="bedrock-runtime",
|
||||
region_name="us-east-1",
|
||||
aws_access_key_id="",
|
||||
aws_secret_access_key="",
|
||||
aws_session_token="",
|
||||
)
|
||||
|
||||
response = completion(
|
||||
model="bedrock/anthropic.claude-instant-v1",
|
||||
messages=[{ "content": "Hello, how are you?","role": "user"}],
|
||||
aws_bedrock_client=bedrock,
|
||||
)
|
||||
```
|
||||
|
||||
Create a client from AWS profile in `~/.aws/config`:
|
||||
```python
|
||||
import boto3
|
||||
from litellm import completion
|
||||
|
||||
dev_session = boto3.Session(profile_name="dev-profile")
|
||||
bedrock = dev_session.client(
|
||||
service_name="bedrock-runtime",
|
||||
region_name="us-east-1",
|
||||
)
|
||||
|
||||
response = completion(
|
||||
model="bedrock/anthropic.claude-instant-v1",
|
||||
messages=[{ "content": "Hello, how are you?","role": "user"}],
|
||||
aws_bedrock_client=bedrock,
|
||||
)
|
||||
```
|
||||
|
||||
|
||||
## Provisioned throughput models
|
||||
To use provisioned throughput Bedrock models pass
|
||||
- `model=bedrock/<base-model>`, example `model=bedrock/anthropic.claude-v2`. Set `model` to any of the [Supported AWS models](#supported-aws-bedrock-models)
|
||||
|
|
|
|||
|
|
@ -46,13 +46,13 @@ for chunk in response:
|
|||
## Supported Models - ALL Groq Models Supported!
|
||||
We support ALL Groq models, just set `groq/` as a prefix when sending completion requests
|
||||
|
||||
| Model Name | Function Call |
|
||||
|--------------------------|------------------------------------------------------------------------------------------------------------------------------------------------------------------|
|
||||
| llama3-8b-8192 | `completion(model="groq/llama3-8b-8192", messages)` |
|
||||
| llama3-70b-8192 | `completion(model="groq/llama3-70b-8192", messages)` |
|
||||
| llama2-70b-4096 | `completion(model="groq/llama2-70b-4096", messages)` |
|
||||
| Model Name | Function Call |
|
||||
|--------------------|---------------------------------------------------------|
|
||||
| llama3-8b-8192 | `completion(model="groq/llama3-8b-8192", messages)` |
|
||||
| llama3-70b-8192 | `completion(model="groq/llama3-70b-8192", messages)` |
|
||||
| llama2-70b-4096 | `completion(model="groq/llama2-70b-4096", messages)` |
|
||||
| mixtral-8x7b-32768 | `completion(model="groq/mixtral-8x7b-32768", messages)` |
|
||||
| gemma-7b-it | `completion(model="groq/gemma-7b-it", messages)` |
|
||||
| gemma-7b-it | `completion(model="groq/gemma-7b-it", messages)` |
|
||||
|
||||
## Groq - Tool / Function Calling Example
|
||||
|
||||
|
|
|
|||
|
|
@ -26,52 +26,52 @@ Example TogetherAI Usage - Note: liteLLM supports all models deployed on Togethe
|
|||
|
||||
|
||||
### Llama LLMs - Chat
|
||||
| Model Name | Function Call | Required OS Variables |
|
||||
|-----------------------------------|------------------------------------------------------------------------|---------------------------------|
|
||||
| togethercomputer/llama-2-70b-chat | `completion('together_ai/togethercomputer/llama-2-70b-chat', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| Model Name | Function Call | Required OS Variables |
|
||||
|-----------------------------------|-------------------------------------------------------------------------|------------------------------------|
|
||||
| togethercomputer/llama-2-70b-chat | `completion('together_ai/togethercomputer/llama-2-70b-chat', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
|
||||
### Llama LLMs - Language / Instruct
|
||||
| Model Name | Function Call | Required OS Variables |
|
||||
|-----------------------------------|------------------------------------------------------------------------|---------------------------------|
|
||||
| togethercomputer/llama-2-70b | `completion('together_ai/togethercomputer/llama-2-70b', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| togethercomputer/LLaMA-2-7B-32K | `completion('together_ai/togethercomputer/LLaMA-2-7B-32K', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| togethercomputer/Llama-2-7B-32K-Instruct | `completion('together_ai/togethercomputer/Llama-2-7B-32K-Instruct', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| togethercomputer/llama-2-7b | `completion('together_ai/togethercomputer/llama-2-7b', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| Model Name | Function Call | Required OS Variables |
|
||||
|------------------------------------------|--------------------------------------------------------------------------------|------------------------------------|
|
||||
| togethercomputer/llama-2-70b | `completion('together_ai/togethercomputer/llama-2-70b', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| togethercomputer/LLaMA-2-7B-32K | `completion('together_ai/togethercomputer/LLaMA-2-7B-32K', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| togethercomputer/Llama-2-7B-32K-Instruct | `completion('together_ai/togethercomputer/Llama-2-7B-32K-Instruct', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| togethercomputer/llama-2-7b | `completion('together_ai/togethercomputer/llama-2-7b', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
|
||||
### Falcon LLMs
|
||||
| Model Name | Function Call | Required OS Variables |
|
||||
|-----------------------------------|------------------------------------------------------------------------|---------------------------------|
|
||||
| togethercomputer/falcon-40b-instruct | `completion('together_ai/togethercomputer/falcon-40b-instruct', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| togethercomputer/falcon-7b-instruct | `completion('together_ai/togethercomputer/falcon-7b-instruct', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| Model Name | Function Call | Required OS Variables |
|
||||
|--------------------------------------|----------------------------------------------------------------------------|------------------------------------|
|
||||
| togethercomputer/falcon-40b-instruct | `completion('together_ai/togethercomputer/falcon-40b-instruct', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| togethercomputer/falcon-7b-instruct | `completion('together_ai/togethercomputer/falcon-7b-instruct', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
|
||||
### Alpaca LLMs
|
||||
| Model Name | Function Call | Required OS Variables |
|
||||
|-----------------------------------|------------------------------------------------------------------------|---------------------------------|
|
||||
| togethercomputer/alpaca-7b | `completion('together_ai/togethercomputer/alpaca-7b', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| Model Name | Function Call | Required OS Variables |
|
||||
|----------------------------|------------------------------------------------------------------|------------------------------------|
|
||||
| togethercomputer/alpaca-7b | `completion('together_ai/togethercomputer/alpaca-7b', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
|
||||
### Other Chat LLMs
|
||||
| Model Name | Function Call | Required OS Variables |
|
||||
|-----------------------------------|------------------------------------------------------------------------|---------------------------------|
|
||||
| HuggingFaceH4/starchat-alpha | `completion('together_ai/HuggingFaceH4/starchat-alpha', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| Model Name | Function Call | Required OS Variables |
|
||||
|------------------------------|--------------------------------------------------------------------|------------------------------------|
|
||||
| HuggingFaceH4/starchat-alpha | `completion('together_ai/HuggingFaceH4/starchat-alpha', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
|
||||
### Code LLMs
|
||||
| Model Name | Function Call | Required OS Variables |
|
||||
|-----------------------------------|------------------------------------------------------------------------|---------------------------------|
|
||||
| togethercomputer/CodeLlama-34b | `completion('together_ai/togethercomputer/CodeLlama-34b', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| togethercomputer/CodeLlama-34b-Instruct | `completion('together_ai/togethercomputer/CodeLlama-34b-Instruct', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| togethercomputer/CodeLlama-34b-Python | `completion('together_ai/togethercomputer/CodeLlama-34b-Python', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| defog/sqlcoder | `completion('together_ai/defog/sqlcoder', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| NumbersStation/nsql-llama-2-7B | `completion('together_ai/NumbersStation/nsql-llama-2-7B', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| WizardLM/WizardCoder-15B-V1.0 | `completion('together_ai/WizardLM/WizardCoder-15B-V1.0', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| WizardLM/WizardCoder-Python-34B-V1.0 | `completion('together_ai/WizardLM/WizardCoder-Python-34B-V1.0', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| Model Name | Function Call | Required OS Variables |
|
||||
|-----------------------------------------|-------------------------------------------------------------------------------|------------------------------------|
|
||||
| togethercomputer/CodeLlama-34b | `completion('together_ai/togethercomputer/CodeLlama-34b', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| togethercomputer/CodeLlama-34b-Instruct | `completion('together_ai/togethercomputer/CodeLlama-34b-Instruct', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| togethercomputer/CodeLlama-34b-Python | `completion('together_ai/togethercomputer/CodeLlama-34b-Python', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| defog/sqlcoder | `completion('together_ai/defog/sqlcoder', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| NumbersStation/nsql-llama-2-7B | `completion('together_ai/NumbersStation/nsql-llama-2-7B', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| WizardLM/WizardCoder-15B-V1.0 | `completion('together_ai/WizardLM/WizardCoder-15B-V1.0', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| WizardLM/WizardCoder-Python-34B-V1.0 | `completion('together_ai/WizardLM/WizardCoder-Python-34B-V1.0', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
|
||||
### Language LLMs
|
||||
| Model Name | Function Call | Required OS Variables |
|
||||
|-----------------------------------|------------------------------------------------------------------------|---------------------------------|
|
||||
| NousResearch/Nous-Hermes-Llama2-13b | `completion('together_ai/NousResearch/Nous-Hermes-Llama2-13b', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| Austism/chronos-hermes-13b | `completion('together_ai/Austism/chronos-hermes-13b', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| upstage/SOLAR-0-70b-16bit | `completion('together_ai/upstage/SOLAR-0-70b-16bit', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| WizardLM/WizardLM-70B-V1.0 | `completion('together_ai/WizardLM/WizardLM-70B-V1.0', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| Model Name | Function Call | Required OS Variables |
|
||||
|-------------------------------------|---------------------------------------------------------------------------|------------------------------------|
|
||||
| NousResearch/Nous-Hermes-Llama2-13b | `completion('together_ai/NousResearch/Nous-Hermes-Llama2-13b', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| Austism/chronos-hermes-13b | `completion('together_ai/Austism/chronos-hermes-13b', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| upstage/SOLAR-0-70b-16bit | `completion('together_ai/upstage/SOLAR-0-70b-16bit', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
| WizardLM/WizardLM-70B-V1.0 | `completion('together_ai/WizardLM/WizardLM-70B-V1.0', messages)` | `os.environ['TOGETHERAI_API_KEY']` |
|
||||
|
||||
|
||||
## Prompt Templates
|
||||
|
|
|
|||
|
|
@ -155,14 +155,14 @@ def default_pt(messages):
|
|||
|
||||
#### Models we already have Prompt Templates for
|
||||
|
||||
| Model Name | Works for Models | Function Call |
|
||||
| -------- | -------- | -------- |
|
||||
| meta-llama/Llama-2-7b-chat | All meta-llama llama2 chat models| `completion(model='vllm/meta-llama/Llama-2-7b', messages=messages, api_base="your_api_endpoint")` |
|
||||
| tiiuae/falcon-7b-instruct | All falcon instruct models | `completion(model='vllm/tiiuae/falcon-7b-instruct', messages=messages, api_base="your_api_endpoint")` |
|
||||
| mosaicml/mpt-7b-chat | All mpt chat models | `completion(model='vllm/mosaicml/mpt-7b-chat', messages=messages, api_base="your_api_endpoint")` |
|
||||
| codellama/CodeLlama-34b-Instruct-hf | All codellama instruct models | `completion(model='vllm/codellama/CodeLlama-34b-Instruct-hf', messages=messages, api_base="your_api_endpoint")` |
|
||||
| WizardLM/WizardCoder-Python-34B-V1.0 | All wizardcoder models | `completion(model='vllm/WizardLM/WizardCoder-Python-34B-V1.0', messages=messages, api_base="your_api_endpoint")` |
|
||||
| Phind/Phind-CodeLlama-34B-v2 | All phind-codellama models | `completion(model='vllm/Phind/Phind-CodeLlama-34B-v2', messages=messages, api_base="your_api_endpoint")` |
|
||||
| Model Name | Works for Models | Function Call |
|
||||
|--------------------------------------|-----------------------------------|------------------------------------------------------------------------------------------------------------------|
|
||||
| meta-llama/Llama-2-7b-chat | All meta-llama llama2 chat models | `completion(model='vllm/meta-llama/Llama-2-7b', messages=messages, api_base="your_api_endpoint")` |
|
||||
| tiiuae/falcon-7b-instruct | All falcon instruct models | `completion(model='vllm/tiiuae/falcon-7b-instruct', messages=messages, api_base="your_api_endpoint")` |
|
||||
| mosaicml/mpt-7b-chat | All mpt chat models | `completion(model='vllm/mosaicml/mpt-7b-chat', messages=messages, api_base="your_api_endpoint")` |
|
||||
| codellama/CodeLlama-34b-Instruct-hf | All codellama instruct models | `completion(model='vllm/codellama/CodeLlama-34b-Instruct-hf', messages=messages, api_base="your_api_endpoint")` |
|
||||
| WizardLM/WizardCoder-Python-34B-V1.0 | All wizardcoder models | `completion(model='vllm/WizardLM/WizardCoder-Python-34B-V1.0', messages=messages, api_base="your_api_endpoint")` |
|
||||
| Phind/Phind-CodeLlama-34B-v2 | All phind-codellama models | `completion(model='vllm/Phind/Phind-CodeLlama-34B-v2', messages=messages, api_base="your_api_endpoint")` |
|
||||
|
||||
#### Custom prompt templates
|
||||
|
||||
|
|
|
|||
|
|
@ -251,23 +251,23 @@ response = completion(
|
|||
|
||||
Here are some examples of models available in IBM watsonx.ai that you can use with LiteLLM:
|
||||
|
||||
| Mode Name | Command |
|
||||
| ---------- | --------- |
|
||||
| Flan T5 XXL | `completion(model=watsonx/google/flan-t5-xxl, messages=messages)` |
|
||||
| Flan Ul2 | `completion(model=watsonx/google/flan-ul2, messages=messages)` |
|
||||
| Mt0 XXL | `completion(model=watsonx/bigscience/mt0-xxl, messages=messages)` |
|
||||
| Gpt Neox | `completion(model=watsonx/eleutherai/gpt-neox-20b, messages=messages)` |
|
||||
| Mpt 7B Instruct2 | `completion(model=watsonx/ibm/mpt-7b-instruct2, messages=messages)` |
|
||||
| Starcoder | `completion(model=watsonx/bigcode/starcoder, messages=messages)` |
|
||||
| Llama 2 70B Chat | `completion(model=watsonx/meta-llama/llama-2-70b-chat, messages=messages)` |
|
||||
| Llama 2 13B Chat | `completion(model=watsonx/meta-llama/llama-2-13b-chat, messages=messages)` |
|
||||
| Granite 13B Instruct | `completion(model=watsonx/ibm/granite-13b-instruct-v1, messages=messages)` |
|
||||
| Granite 13B Chat | `completion(model=watsonx/ibm/granite-13b-chat-v1, messages=messages)` |
|
||||
| Flan T5 XL | `completion(model=watsonx/google/flan-t5-xl, messages=messages)` |
|
||||
| Granite 13B Chat V2 | `completion(model=watsonx/ibm/granite-13b-chat-v2, messages=messages)` |
|
||||
| Granite 13B Instruct V2 | `completion(model=watsonx/ibm/granite-13b-instruct-v2, messages=messages)` |
|
||||
| Elyza Japanese Llama 2 7B Instruct | `completion(model=watsonx/elyza/elyza-japanese-llama-2-7b-instruct, messages=messages)` |
|
||||
| Mixtral 8X7B Instruct V01 Q | `completion(model=watsonx/ibm-mistralai/mixtral-8x7b-instruct-v01-q, messages=messages)` |
|
||||
| Mode Name | Command |
|
||||
|------------------------------------|------------------------------------------------------------------------------------------|
|
||||
| Flan T5 XXL | `completion(model=watsonx/google/flan-t5-xxl, messages=messages)` |
|
||||
| Flan Ul2 | `completion(model=watsonx/google/flan-ul2, messages=messages)` |
|
||||
| Mt0 XXL | `completion(model=watsonx/bigscience/mt0-xxl, messages=messages)` |
|
||||
| Gpt Neox | `completion(model=watsonx/eleutherai/gpt-neox-20b, messages=messages)` |
|
||||
| Mpt 7B Instruct2 | `completion(model=watsonx/ibm/mpt-7b-instruct2, messages=messages)` |
|
||||
| Starcoder | `completion(model=watsonx/bigcode/starcoder, messages=messages)` |
|
||||
| Llama 2 70B Chat | `completion(model=watsonx/meta-llama/llama-2-70b-chat, messages=messages)` |
|
||||
| Llama 2 13B Chat | `completion(model=watsonx/meta-llama/llama-2-13b-chat, messages=messages)` |
|
||||
| Granite 13B Instruct | `completion(model=watsonx/ibm/granite-13b-instruct-v1, messages=messages)` |
|
||||
| Granite 13B Chat | `completion(model=watsonx/ibm/granite-13b-chat-v1, messages=messages)` |
|
||||
| Flan T5 XL | `completion(model=watsonx/google/flan-t5-xl, messages=messages)` |
|
||||
| Granite 13B Chat V2 | `completion(model=watsonx/ibm/granite-13b-chat-v2, messages=messages)` |
|
||||
| Granite 13B Instruct V2 | `completion(model=watsonx/ibm/granite-13b-instruct-v2, messages=messages)` |
|
||||
| Elyza Japanese Llama 2 7B Instruct | `completion(model=watsonx/elyza/elyza-japanese-llama-2-7b-instruct, messages=messages)` |
|
||||
| Mixtral 8X7B Instruct V01 Q | `completion(model=watsonx/ibm-mistralai/mixtral-8x7b-instruct-v01-q, messages=messages)` |
|
||||
|
||||
|
||||
For a list of all available models in watsonx.ai, see [here](https://dataplatform.cloud.ibm.com/docs/content/wsj/analyze-data/fm-models.html?context=wx&locale=en&audience=wdp).
|
||||
|
|
@ -275,10 +275,10 @@ For a list of all available models in watsonx.ai, see [here](https://dataplatfor
|
|||
|
||||
## Supported IBM watsonx.ai Embedding Models
|
||||
|
||||
| Model Name | Function Call |
|
||||
|----------------------|---------------------------------------------|
|
||||
| Slate 30m | `embedding(model="watsonx/ibm/slate-30m-english-rtrvr", input=input)` |
|
||||
| Slate 125m | `embedding(model="watsonx/ibm/slate-125m-english-rtrvr", input=input)` |
|
||||
| Model Name | Function Call |
|
||||
|------------|------------------------------------------------------------------------|
|
||||
| Slate 30m | `embedding(model="watsonx/ibm/slate-30m-english-rtrvr", input=input)` |
|
||||
| Slate 125m | `embedding(model="watsonx/ibm/slate-125m-english-rtrvr", input=input)` |
|
||||
|
||||
|
||||
For a list of all available embedding models in watsonx.ai, see [here](https://dataplatform.cloud.ibm.com/docs/content/wsj/analyze-data/fm-models-embed.html?context=wx).
|
||||
|
|
@ -37,26 +37,26 @@ print(response)
|
|||
## Supported Models
|
||||
All models listed here https://inference.readthedocs.io/en/latest/models/builtin/embedding/index.html are supported
|
||||
|
||||
| Model Name | Function Call |
|
||||
|------------------------------|--------------------------------------------------------|
|
||||
| bge-base-en | `embedding(model="xinference/bge-base-en", input)` |
|
||||
| bge-base-en-v1.5 | `embedding(model="xinference/bge-base-en-v1.5", input)` |
|
||||
| bge-base-zh | `embedding(model="xinference/bge-base-zh", input)` |
|
||||
| bge-base-zh-v1.5 | `embedding(model="xinference/bge-base-zh-v1.5", input)` |
|
||||
| bge-large-en | `embedding(model="xinference/bge-large-en", input)` |
|
||||
| bge-large-en-v1.5 | `embedding(model="xinference/bge-large-en-v1.5", input)` |
|
||||
| bge-large-zh | `embedding(model="xinference/bge-large-zh", input)` |
|
||||
| bge-large-zh-noinstruct | `embedding(model="xinference/bge-large-zh-noinstruct", input)` |
|
||||
| bge-large-zh-v1.5 | `embedding(model="xinference/bge-large-zh-v1.5", input)` |
|
||||
| bge-small-en-v1.5 | `embedding(model="xinference/bge-small-en-v1.5", input)` |
|
||||
| bge-small-zh | `embedding(model="xinference/bge-small-zh", input)` |
|
||||
| bge-small-zh-v1.5 | `embedding(model="xinference/bge-small-zh-v1.5", input)` |
|
||||
| e5-large-v2 | `embedding(model="xinference/e5-large-v2", input)` |
|
||||
| gte-base | `embedding(model="xinference/gte-base", input)` |
|
||||
| gte-large | `embedding(model="xinference/gte-large", input)` |
|
||||
| jina-embeddings-v2-base-en | `embedding(model="xinference/jina-embeddings-v2-base-en", input)` |
|
||||
| jina-embeddings-v2-small-en | `embedding(model="xinference/jina-embeddings-v2-small-en", input)` |
|
||||
| multilingual-e5-large | `embedding(model="xinference/multilingual-e5-large", input)` |
|
||||
| Model Name | Function Call |
|
||||
|-----------------------------|--------------------------------------------------------------------|
|
||||
| bge-base-en | `embedding(model="xinference/bge-base-en", input)` |
|
||||
| bge-base-en-v1.5 | `embedding(model="xinference/bge-base-en-v1.5", input)` |
|
||||
| bge-base-zh | `embedding(model="xinference/bge-base-zh", input)` |
|
||||
| bge-base-zh-v1.5 | `embedding(model="xinference/bge-base-zh-v1.5", input)` |
|
||||
| bge-large-en | `embedding(model="xinference/bge-large-en", input)` |
|
||||
| bge-large-en-v1.5 | `embedding(model="xinference/bge-large-en-v1.5", input)` |
|
||||
| bge-large-zh | `embedding(model="xinference/bge-large-zh", input)` |
|
||||
| bge-large-zh-noinstruct | `embedding(model="xinference/bge-large-zh-noinstruct", input)` |
|
||||
| bge-large-zh-v1.5 | `embedding(model="xinference/bge-large-zh-v1.5", input)` |
|
||||
| bge-small-en-v1.5 | `embedding(model="xinference/bge-small-en-v1.5", input)` |
|
||||
| bge-small-zh | `embedding(model="xinference/bge-small-zh", input)` |
|
||||
| bge-small-zh-v1.5 | `embedding(model="xinference/bge-small-zh-v1.5", input)` |
|
||||
| e5-large-v2 | `embedding(model="xinference/e5-large-v2", input)` |
|
||||
| gte-base | `embedding(model="xinference/gte-base", input)` |
|
||||
| gte-large | `embedding(model="xinference/gte-large", input)` |
|
||||
| jina-embeddings-v2-base-en | `embedding(model="xinference/jina-embeddings-v2-base-en", input)` |
|
||||
| jina-embeddings-v2-small-en | `embedding(model="xinference/jina-embeddings-v2-small-en", input)` |
|
||||
| multilingual-e5-large | `embedding(model="xinference/multilingual-e5-large", input)` |
|
||||
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -62,6 +62,23 @@ curl -X GET 'http://localhost:4000/health/services?service=slack' \
|
|||
-H 'Authorization: Bearer sk-1234'
|
||||
```
|
||||
|
||||
## Advanced - Redacting Messages from Alerts
|
||||
|
||||
By default alerts show the `messages/input` passed to the LLM. If you want to redact this from slack alerting set the following setting on your config
|
||||
|
||||
|
||||
```shell
|
||||
general_settings:
|
||||
alerting: ["slack"]
|
||||
alert_types: ["spend_reports"]
|
||||
|
||||
litellm_settings:
|
||||
redact_messages_in_exceptions: True
|
||||
```
|
||||
|
||||
|
||||
|
||||
|
||||
## Advanced - Opting into specific alert types
|
||||
|
||||
Set `alert_types` if you want to Opt into only specific alert types
|
||||
|
|
|
|||
|
|
@ -283,7 +283,7 @@ litellm_settings:
|
|||
|
||||
### Turn on / off caching per request.
|
||||
|
||||
The proxy support 3 cache-controls:
|
||||
The proxy support 4 cache-controls:
|
||||
|
||||
- `ttl`: *Optional(int)* - Will cache the response for the user-defined amount of time (in seconds).
|
||||
- `s-maxage`: *Optional(int)* Will only accept cached responses that are within user-defined range (in seconds).
|
||||
|
|
@ -374,6 +374,33 @@ chat_completion = client.chat.completions.create(
|
|||
)
|
||||
```
|
||||
|
||||
### Turn on / off caching per Key.
|
||||
|
||||
1. Add cache params when creating a key [full list](#turn-on--off-caching-per-key)
|
||||
|
||||
```bash
|
||||
curl -X POST 'http://0.0.0.0:4000/key/generate' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-D '{
|
||||
"user_id": "222",
|
||||
"metadata": {
|
||||
"cache": {
|
||||
"no-cache": true
|
||||
}
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
2. Test it!
|
||||
|
||||
```bash
|
||||
curl -X POST 'http://localhost:4000/chat/completions' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-H 'Authorization: Bearer <YOUR_NEW_KEY>' \
|
||||
-D '{"model": "gpt-3.5-turbo", "messages": [{"role": "user", "content": "bom dia"}]}'
|
||||
```
|
||||
|
||||
### Deleting Cache Keys - `/cache/delete`
|
||||
In order to delete a cache key, send a request to `/cache/delete` with the `keys` you want to delete
|
||||
|
||||
|
|
|
|||
|
|
@ -80,6 +80,13 @@ For more provider-specific info, [go here](../providers/)
|
|||
$ litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
:::tip
|
||||
|
||||
Run with `--detailed_debug` if you need detailed debug logs
|
||||
|
||||
```shell
|
||||
$ litellm --config /path/to/config.yaml --detailed_debug
|
||||
:::
|
||||
|
||||
### Using Proxy - Curl Request, OpenAI Package, Langchain, Langchain JS
|
||||
Calling a model group
|
||||
|
|
|
|||
|
|
@ -1,22 +1,163 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
import Image from '@theme/IdealImage';
|
||||
|
||||
# 💸 Spend Tracking
|
||||
|
||||
Track spend for keys, users, and teams across 100+ LLMs.
|
||||
|
||||
## Getting Spend Reports - To Charge Other Teams, API Keys
|
||||
### How to Track Spend with LiteLLM
|
||||
|
||||
Use the `/global/spend/report` endpoint to get daily spend per team, with a breakdown of spend per API Key, Model
|
||||
**Step 1**
|
||||
|
||||
### Example Request
|
||||
👉 [Setup LiteLLM with a Database](https://docs.litellm.ai/docs/proxy/deploy)
|
||||
|
||||
|
||||
**Step2** Send `/chat/completions` request
|
||||
|
||||
<Tabs>
|
||||
|
||||
|
||||
<TabItem value="openai" label="OpenAI Python v1.0.0+">
|
||||
|
||||
```python
|
||||
import openai
|
||||
client = openai.OpenAI(
|
||||
api_key="sk-1234",
|
||||
base_url="http://0.0.0.0:4000"
|
||||
)
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="llama3",
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "this is a test request, write a short poem"
|
||||
}
|
||||
],
|
||||
user="palantir",
|
||||
extra_body={
|
||||
"metadata": {
|
||||
"tags": ["jobID:214590dsff09fds", "taskName:run_page_classification"]
|
||||
}
|
||||
}
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="Curl" label="Curl Request">
|
||||
|
||||
Pass `metadata` as part of the request body
|
||||
|
||||
```shell
|
||||
curl -X GET 'http://localhost:4000/global/spend/report?start_date=2024-04-01&end_date=2024-06-30' \
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer sk-1234' \
|
||||
--data '{
|
||||
"model": "llama3",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
"user": "palantir",
|
||||
"metadata": {
|
||||
"tags": ["jobID:214590dsff09fds", "taskName:run_page_classification"]
|
||||
}
|
||||
}'
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="langchain" label="Langchain">
|
||||
|
||||
```python
|
||||
from langchain.chat_models import ChatOpenAI
|
||||
from langchain.prompts.chat import (
|
||||
ChatPromptTemplate,
|
||||
HumanMessagePromptTemplate,
|
||||
SystemMessagePromptTemplate,
|
||||
)
|
||||
from langchain.schema import HumanMessage, SystemMessage
|
||||
import os
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "sk-1234"
|
||||
|
||||
chat = ChatOpenAI(
|
||||
openai_api_base="http://0.0.0.0:4000",
|
||||
model = "llama3",
|
||||
user="palantir",
|
||||
extra_body={
|
||||
"metadata": {
|
||||
"tags": ["jobID:214590dsff09fds", "taskName:run_page_classification"]
|
||||
}
|
||||
}
|
||||
)
|
||||
|
||||
messages = [
|
||||
SystemMessage(
|
||||
content="You are a helpful assistant that im using to make a test request to."
|
||||
),
|
||||
HumanMessage(
|
||||
content="test from litellm. tell me why it's amazing in 1 sentence"
|
||||
),
|
||||
]
|
||||
response = chat(messages)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
**Step3 - Verify Spend Tracked**
|
||||
That's IT. Now Verify your spend was tracked
|
||||
|
||||
The following spend gets tracked in Table `LiteLLM_SpendLogs`
|
||||
|
||||
```json
|
||||
{
|
||||
"api_key": "fe6b0cab4ff5a5a8df823196cc8a450*****", # Hash of API Key used
|
||||
"user": "default_user", # Internal User (LiteLLM_UserTable) that owns `api_key=sk-1234`.
|
||||
"team_id": "e8d1460f-846c-45d7-9b43-55f3cc52ac32", # Team (LiteLLM_TeamTable) that owns `api_key=sk-1234`
|
||||
"request_tags": ["jobID:214590dsff09fds", "taskName:run_page_classification"],# Tags sent in request
|
||||
"end_user": "palantir", # Customer - the `user` sent in the request
|
||||
"model_group": "llama3", # "model" passed to LiteLLM
|
||||
"api_base": "https://api.groq.com/openai/v1/", # "api_base" of model used by LiteLLM
|
||||
"spend": 0.000002, # Spend in $
|
||||
"total_tokens": 100,
|
||||
"completion_tokens": 80,
|
||||
"prompt_tokens": 20,
|
||||
|
||||
}
|
||||
```
|
||||
|
||||
Navigate to the Usage Tab on the LiteLLM UI (found on https://your-proxy-endpoint/ui) and verify you see spend tracked under `Usage`
|
||||
|
||||
<Image img={require('../../img/admin_ui_spend.png')} />
|
||||
|
||||
## API Endpoints to get Spend
|
||||
#### Getting Spend Reports - To Charge Other Teams, Customers
|
||||
|
||||
Use the `/global/spend/report` endpoint to get daily spend report per
|
||||
- team
|
||||
- customer [this is `user` passed to `/chat/completions` request](#how-to-track-spend-with-litellm)
|
||||
|
||||
<Tabs>
|
||||
|
||||
<TabItem value="per team" label="Spend Per Team">
|
||||
|
||||
##### Example Request
|
||||
|
||||
👉 Key Change: Specify `group_by=team`
|
||||
|
||||
```shell
|
||||
curl -X GET 'http://localhost:4000/global/spend/report?start_date=2024-04-01&end_date=2024-06-30&group_by=team' \
|
||||
-H 'Authorization: Bearer sk-1234'
|
||||
```
|
||||
|
||||
### Example Response
|
||||
##### Example Response
|
||||
<Tabs>
|
||||
|
||||
<TabItem value="response" label="Expected Response">
|
||||
|
|
@ -125,7 +266,70 @@ Output from script
|
|||
|
||||
</Tabs>
|
||||
|
||||
## Allowing Non-Proxy Admins to access `/spend` endpoints
|
||||
</TabItem>
|
||||
|
||||
|
||||
<TabItem value="per customer" label="Spend Per Customer">
|
||||
|
||||
##### Example Request
|
||||
|
||||
👉 Key Change: Specify `group_by=customer`
|
||||
|
||||
|
||||
```shell
|
||||
curl -X GET 'http://localhost:4000/global/spend/report?start_date=2024-04-01&end_date=2024-06-30&group_by=customer' \
|
||||
-H 'Authorization: Bearer sk-1234'
|
||||
```
|
||||
|
||||
##### Example Response
|
||||
|
||||
|
||||
```shell
|
||||
[
|
||||
{
|
||||
"group_by_day": "2024-04-30T00:00:00+00:00",
|
||||
"customers": [
|
||||
{
|
||||
"customer": "palantir",
|
||||
"total_spend": 0.0015265,
|
||||
"metadata": [ # see the spend by unique(key + model)
|
||||
{
|
||||
"model": "gpt-4",
|
||||
"spend": 0.00123,
|
||||
"total_tokens": 28,
|
||||
"api_key": "88dc28.." # the hashed api key
|
||||
},
|
||||
{
|
||||
"model": "gpt-4",
|
||||
"spend": 0.00123,
|
||||
"total_tokens": 28,
|
||||
"api_key": "a73dc2.." # the hashed api key
|
||||
},
|
||||
{
|
||||
"model": "chatgpt-v-2",
|
||||
"spend": 0.000214,
|
||||
"total_tokens": 122,
|
||||
"api_key": "898c28.." # the hashed api key
|
||||
},
|
||||
{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"spend": 0.0000825,
|
||||
"total_tokens": 85,
|
||||
"api_key": "84dc28.." # the hashed api key
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
|
||||
</TabItem>
|
||||
|
||||
</Tabs>
|
||||
|
||||
#### Allowing Non-Proxy Admins to access `/spend` endpoints
|
||||
|
||||
Use this when you want non-proxy admins to access `/spend` endpoints
|
||||
|
||||
|
|
@ -135,7 +339,7 @@ Schedule a [meeting with us to get your Enterprise License](https://calendly.com
|
|||
|
||||
:::
|
||||
|
||||
### Create Key
|
||||
##### Create Key
|
||||
Create Key with with `permissions={"get_spend_routes": true}`
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/key/generate' \
|
||||
|
|
@ -146,7 +350,7 @@ curl --location 'http://0.0.0.0:4000/key/generate' \
|
|||
}'
|
||||
```
|
||||
|
||||
### Use generated key on `/spend` endpoints
|
||||
##### Use generated key on `/spend` endpoints
|
||||
|
||||
Access spend Routes with newly generate keys
|
||||
```shell
|
||||
|
|
@ -156,14 +360,14 @@ curl -X GET 'http://localhost:4000/global/spend/report?start_date=2024-04-01&end
|
|||
|
||||
|
||||
|
||||
## Reset Team, API Key Spend - MASTER KEY ONLY
|
||||
#### Reset Team, API Key Spend - MASTER KEY ONLY
|
||||
|
||||
Use `/global/spend/reset` if you want to:
|
||||
- Reset the Spend for all API Keys, Teams. The `spend` for ALL Teams and Keys in `LiteLLM_TeamTable` and `LiteLLM_VerificationToken` will be set to `spend=0`
|
||||
|
||||
- LiteLLM will maintain all the logs in `LiteLLMSpendLogs` for Auditing Purposes
|
||||
|
||||
### Request
|
||||
##### Request
|
||||
Only the `LITELLM_MASTER_KEY` you set can access this route
|
||||
```shell
|
||||
curl -X POST \
|
||||
|
|
@ -172,7 +376,7 @@ curl -X POST \
|
|||
-H 'Content-Type: application/json'
|
||||
```
|
||||
|
||||
### Expected Responses
|
||||
##### Expected Responses
|
||||
|
||||
```shell
|
||||
{"message":"Spend for all API Keys and Teams reset successfully","status":"success"}
|
||||
|
|
@ -181,11 +385,11 @@ curl -X POST \
|
|||
|
||||
|
||||
|
||||
## Spend Tracking for Azure
|
||||
## Spend Tracking for Azure OpenAI Models
|
||||
|
||||
Set base model for cost tracking azure image-gen call
|
||||
|
||||
### Image Generation
|
||||
#### Image Generation
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
|
|
@ -200,7 +404,7 @@ model_list:
|
|||
mode: image_generation
|
||||
```
|
||||
|
||||
### Chat Completions / Embeddings
|
||||
#### Chat Completions / Embeddings
|
||||
|
||||
**Problem**: Azure returns `gpt-4` in the response when `azure/gpt-4-1106-preview` is used. This leads to inaccurate cost tracking
|
||||
|
||||
|
|
@ -219,4 +423,8 @@ model_list:
|
|||
api_version: "2023-07-01-preview"
|
||||
model_info:
|
||||
base_model: azure/gpt-4-1106-preview
|
||||
```
|
||||
```
|
||||
|
||||
## Custom Input/Output Pricing
|
||||
|
||||
👉 Head to [Custom Input/Output Pricing](https://docs.litellm.ai/docs/proxy/custom_pricing) to setup custom pricing or your models
|
||||
|
|
@ -42,6 +42,14 @@ Set `JSON_LOGS="True"` in your env:
|
|||
```bash
|
||||
export JSON_LOGS="True"
|
||||
```
|
||||
**OR**
|
||||
|
||||
Set `json_logs: true` in your yaml:
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
json_logs: true
|
||||
```
|
||||
|
||||
Start proxy
|
||||
|
||||
|
|
@ -49,4 +57,35 @@ Start proxy
|
|||
$ litellm
|
||||
```
|
||||
|
||||
The proxy will now all logs in json format.
|
||||
The proxy will now all logs in json format.
|
||||
|
||||
## Control Log Output
|
||||
|
||||
Turn off fastapi's default 'INFO' logs
|
||||
|
||||
1. Turn on 'json logs'
|
||||
```yaml
|
||||
litellm_settings:
|
||||
json_logs: true
|
||||
```
|
||||
|
||||
2. Set `LITELLM_LOG` to 'ERROR'
|
||||
|
||||
Only get logs if an error occurs.
|
||||
|
||||
```bash
|
||||
LITELLM_LOG="ERROR"
|
||||
```
|
||||
|
||||
3. Start proxy
|
||||
|
||||
|
||||
```bash
|
||||
$ litellm
|
||||
```
|
||||
|
||||
Expected Output:
|
||||
|
||||
```bash
|
||||
# no info statements
|
||||
```
|
||||
|
|
@ -7,6 +7,23 @@ You can find the Dockerfile to build litellm proxy [here](https://github.com/Ber
|
|||
|
||||
## Quick Start
|
||||
|
||||
To start using Litellm, run the following commands in a shell:
|
||||
|
||||
```bash
|
||||
# Get the code
|
||||
git clone https://github.com/BerriAI/litellm
|
||||
|
||||
# Go to folder
|
||||
cd litellm
|
||||
|
||||
# Add the master key
|
||||
echo 'LITELLM_MASTER_KEY="sk-1234"' > .env
|
||||
source .env
|
||||
|
||||
# Start
|
||||
docker-compose up
|
||||
```
|
||||
|
||||
<Tabs>
|
||||
|
||||
<TabItem value="basic" label="Basic">
|
||||
|
|
@ -243,7 +260,7 @@ Requirements:
|
|||
|
||||
<TabItem value="docker-deploy" label="Dockerfile">
|
||||
|
||||
We maintain a [seperate Dockerfile](https://github.com/BerriAI/litellm/pkgs/container/litellm-database) for reducing build time when running LiteLLM proxy with a connected Postgres Database
|
||||
We maintain a [separate Dockerfile](https://github.com/BerriAI/litellm/pkgs/container/litellm-database) for reducing build time when running LiteLLM proxy with a connected Postgres Database
|
||||
|
||||
```shell
|
||||
docker pull ghcr.io/berriai/litellm-database:main-latest
|
||||
|
|
|
|||
|
|
@ -2,30 +2,317 @@ import Image from '@theme/IdealImage';
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# ✨ Enterprise Features - Content Mod, SSO, Custom Swagger
|
||||
# ✨ Enterprise Features - SSO, Audit Logs, Guardrails
|
||||
|
||||
Features here are behind a commercial license in our `/enterprise` folder. [**See Code**](https://github.com/BerriAI/litellm/tree/main/enterprise)
|
||||
:::tip
|
||||
|
||||
:::info
|
||||
|
||||
[Get Started with Enterprise here](https://github.com/BerriAI/litellm/tree/main/enterprise)
|
||||
Get in touch with us [here](https://calendly.com/d/4mp-gd3-k5k/litellm-1-1-onboarding-chat)
|
||||
|
||||
:::
|
||||
|
||||
Features:
|
||||
- ✅ [SSO for Admin UI](./ui.md#✨-enterprise-features)
|
||||
- ✅ Content Moderation with LLM Guard, LlamaGuard, Google Text Moderations
|
||||
- ✅ [Prompt Injection Detection (with LakeraAI API)](#prompt-injection-detection-lakeraai)
|
||||
- ✅ [Audit Logs](#audit-logs)
|
||||
- ✅ [Tracking Spend for Custom Tags](#tracking-spend-for-custom-tags)
|
||||
- ✅ [Enforce Required Params for LLM Requests (ex. Reject requests missing ["metadata"]["generation_name"])](#enforce-required-params-for-llm-requests)
|
||||
- ✅ [Content Moderation with LLM Guard, LlamaGuard, Google Text Moderations](#content-moderation)
|
||||
- ✅ [Prompt Injection Detection (with LakeraAI API)](#prompt-injection-detection---lakeraai)
|
||||
- ✅ [Custom Branding + Routes on Swagger Docs](#swagger-docs---custom-routes--branding)
|
||||
- ✅ Reject calls from Blocked User list
|
||||
- ✅ Reject calls (incoming / outgoing) with Banned Keywords (e.g. competitors)
|
||||
- ✅ Don't log/store specific requests to Langfuse, Sentry, etc. (eg confidential LLM requests)
|
||||
- ✅ Tracking Spend for Custom Tags
|
||||
- ✅ Custom Branding + Routes on Swagger Docs
|
||||
- ✅ Audit Logs for `Created At, Created By` when Models Added
|
||||
|
||||
## Audit Logs
|
||||
|
||||
Store Audit logs for **Create, Update Delete Operations** done on `Teams` and `Virtual Keys`
|
||||
|
||||
**Step 1** Switch on audit Logs
|
||||
```shell
|
||||
litellm_settings:
|
||||
store_audit_logs: true
|
||||
```
|
||||
|
||||
Start the litellm proxy with this config
|
||||
|
||||
**Step 2** Test it - Create a Team
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/team/new' \
|
||||
--header 'Authorization: Bearer sk-1234' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"max_budget": 2
|
||||
}'
|
||||
```
|
||||
|
||||
**Step 3** Expected Log
|
||||
|
||||
```json
|
||||
{
|
||||
"id": "e1760e10-4264-4499-82cd-c08c86c8d05b",
|
||||
"updated_at": "2024-06-06T02:10:40.836420+00:00",
|
||||
"changed_by": "109010464461339474872",
|
||||
"action": "created",
|
||||
"table_name": "LiteLLM_TeamTable",
|
||||
"object_id": "82e725b5-053f-459d-9a52-867191635446",
|
||||
"before_value": null,
|
||||
"updated_values": {
|
||||
"team_id": "82e725b5-053f-459d-9a52-867191635446",
|
||||
"admins": [],
|
||||
"members": [],
|
||||
"members_with_roles": [
|
||||
{
|
||||
"role": "admin",
|
||||
"user_id": "109010464461339474872"
|
||||
}
|
||||
],
|
||||
"max_budget": 2.0,
|
||||
"models": [],
|
||||
"blocked": false
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
|
||||
## Tracking Spend for Custom Tags
|
||||
|
||||
Requirements:
|
||||
|
||||
- Virtual Keys & a database should be set up, see [virtual keys](https://docs.litellm.ai/docs/proxy/virtual_keys)
|
||||
|
||||
#### Usage - /chat/completions requests with request tags
|
||||
|
||||
|
||||
<Tabs>
|
||||
|
||||
|
||||
<TabItem value="openai" label="OpenAI Python v1.0.0+">
|
||||
|
||||
Set `extra_body={"metadata": { }}` to `metadata` you want to pass
|
||||
|
||||
```python
|
||||
import openai
|
||||
client = openai.OpenAI(
|
||||
api_key="anything",
|
||||
base_url="http://0.0.0.0:4000"
|
||||
)
|
||||
|
||||
# request sent to model set on litellm proxy, `litellm --model`
|
||||
response = client.chat.completions.create(
|
||||
model="gpt-3.5-turbo",
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "this is a test request, write a short poem"
|
||||
}
|
||||
],
|
||||
extra_body={
|
||||
"metadata": {
|
||||
"tags": ["model-anthropic-claude-v2.1", "app-ishaan-prod"]
|
||||
}
|
||||
}
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="Curl" label="Curl Request">
|
||||
|
||||
Pass `metadata` as part of the request body
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
"metadata": {"tags": ["model-anthropic-claude-v2.1", "app-ishaan-prod"]}
|
||||
}'
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="langchain" label="Langchain">
|
||||
|
||||
```python
|
||||
from langchain.chat_models import ChatOpenAI
|
||||
from langchain.prompts.chat import (
|
||||
ChatPromptTemplate,
|
||||
HumanMessagePromptTemplate,
|
||||
SystemMessagePromptTemplate,
|
||||
)
|
||||
from langchain.schema import HumanMessage, SystemMessage
|
||||
|
||||
chat = ChatOpenAI(
|
||||
openai_api_base="http://0.0.0.0:4000",
|
||||
model = "gpt-3.5-turbo",
|
||||
temperature=0.1,
|
||||
extra_body={
|
||||
"metadata": {
|
||||
"tags": ["model-anthropic-claude-v2.1", "app-ishaan-prod"]
|
||||
}
|
||||
}
|
||||
)
|
||||
|
||||
messages = [
|
||||
SystemMessage(
|
||||
content="You are a helpful assistant that im using to make a test request to."
|
||||
),
|
||||
HumanMessage(
|
||||
content="test from litellm. tell me why it's amazing in 1 sentence"
|
||||
),
|
||||
]
|
||||
response = chat(messages)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
||||
#### Viewing Spend per tag
|
||||
|
||||
#### `/spend/tags` Request Format
|
||||
```shell
|
||||
curl -X GET "http://0.0.0.0:4000/spend/tags" \
|
||||
-H "Authorization: Bearer sk-1234"
|
||||
```
|
||||
|
||||
#### `/spend/tags`Response Format
|
||||
```shell
|
||||
[
|
||||
{
|
||||
"individual_request_tag": "model-anthropic-claude-v2.1",
|
||||
"log_count": 6,
|
||||
"total_spend": 0.000672
|
||||
},
|
||||
{
|
||||
"individual_request_tag": "app-ishaan-local",
|
||||
"log_count": 4,
|
||||
"total_spend": 0.000448
|
||||
},
|
||||
{
|
||||
"individual_request_tag": "app-ishaan-prod",
|
||||
"log_count": 2,
|
||||
"total_spend": 0.000224
|
||||
}
|
||||
]
|
||||
|
||||
```
|
||||
|
||||
|
||||
## Enforce Required Params for LLM Requests
|
||||
Use this when you want to enforce all requests to include certain params. Example you need all requests to include the `user` and `["metadata]["generation_name"]` params.
|
||||
|
||||
**Step 1** Define all Params you want to enforce on config.yaml
|
||||
|
||||
This means `["user"]` and `["metadata]["generation_name"]` are required in all LLM Requests to LiteLLM
|
||||
|
||||
```yaml
|
||||
general_settings:
|
||||
master_key: sk-1234
|
||||
enforced_params:
|
||||
- user
|
||||
- metadata.generation_name
|
||||
```
|
||||
|
||||
Start LiteLLM Proxy
|
||||
|
||||
**Step 2 Verify if this works**
|
||||
|
||||
<Tabs>
|
||||
|
||||
<TabItem value="bad" label="Invalid Request (No `user` passed)">
|
||||
|
||||
```shell
|
||||
curl --location 'http://localhost:4000/chat/completions' \
|
||||
--header 'Authorization: Bearer sk-5fmYeaUEbAMpwBNT-QpxyA' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "hi"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
Expected Response
|
||||
|
||||
```shell
|
||||
{"error":{"message":"Authentication Error, BadRequest please pass param=user in request body. This is a required param","type":"auth_error","param":"None","code":401}}%
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="bad2" label="Invalid Request (No `metadata` passed)">
|
||||
|
||||
```shell
|
||||
curl --location 'http://localhost:4000/chat/completions' \
|
||||
--header 'Authorization: Bearer sk-5fmYeaUEbAMpwBNT-QpxyA' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"user": "gm",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "hi"
|
||||
}
|
||||
],
|
||||
"metadata": {}
|
||||
}'
|
||||
```
|
||||
|
||||
Expected Response
|
||||
|
||||
```shell
|
||||
{"error":{"message":"Authentication Error, BadRequest please pass param=[metadata][generation_name] in request body. This is a required param","type":"auth_error","param":"None","code":401}}%
|
||||
```
|
||||
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="good" label="Valid Request">
|
||||
|
||||
```shell
|
||||
curl --location 'http://localhost:4000/chat/completions' \
|
||||
--header 'Authorization: Bearer sk-5fmYeaUEbAMpwBNT-QpxyA' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"user": "gm",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "hi"
|
||||
}
|
||||
],
|
||||
"metadata": {"generation_name": "prod-app"}
|
||||
}'
|
||||
```
|
||||
|
||||
Expected Response
|
||||
|
||||
```shell
|
||||
{"id":"chatcmpl-9XALnHqkCBMBKrOx7Abg0hURHqYtY","choices":[{"finish_reason":"stop","index":0,"message":{"content":"Hello! How can I assist you today?","role":"assistant"}}],"created":1717691639,"model":"gpt-3.5-turbo-0125","object":"chat.completion","system_fingerprint":null,"usage":{"completion_tokens":9,"prompt_tokens":8,"total_tokens":17}}%
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Content Moderation
|
||||
### Content Moderation with LLM Guard
|
||||
#### Content Moderation with LLM Guard
|
||||
|
||||
Set the LLM Guard API Base in your environment
|
||||
|
||||
|
|
@ -160,7 +447,7 @@ curl --location 'http://0.0.0.0:4000/v1/chat/completions' \
|
|||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Content Moderation with LlamaGuard
|
||||
#### Content Moderation with LlamaGuard
|
||||
|
||||
Currently works with Sagemaker's LlamaGuard endpoint.
|
||||
|
||||
|
|
@ -194,7 +481,7 @@ callbacks: ["llamaguard_moderations"]
|
|||
|
||||
|
||||
|
||||
### Content Moderation with Google Text Moderation
|
||||
#### Content Moderation with Google Text Moderation
|
||||
|
||||
Requires your GOOGLE_APPLICATION_CREDENTIALS to be set in your .env (same as VertexAI).
|
||||
|
||||
|
|
@ -250,7 +537,7 @@ Here are the category specific values:
|
|||
|
||||
|
||||
|
||||
### Content Moderation with OpenAI Moderations
|
||||
#### Content Moderation with OpenAI Moderations
|
||||
|
||||
Use this if you want to reject /chat, /completions, /embeddings calls that fail OpenAI Moderations checks
|
||||
|
||||
|
|
@ -276,7 +563,7 @@ Step 1 Set a `LAKERA_API_KEY` in your env
|
|||
LAKERA_API_KEY="7a91a1a6059da*******"
|
||||
```
|
||||
|
||||
Step 2. Add `lakera_prompt_injection` to your calbacks
|
||||
Step 2. Add `lakera_prompt_injection` to your callbacks
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
|
|
@ -302,6 +589,42 @@ curl --location 'http://localhost:4000/chat/completions' \
|
|||
}'
|
||||
```
|
||||
|
||||
## Swagger Docs - Custom Routes + Branding
|
||||
|
||||
:::info
|
||||
|
||||
Requires a LiteLLM Enterprise key to use. Get a free 2-week license [here](https://forms.gle/sTDVprBs18M4V8Le8)
|
||||
|
||||
:::
|
||||
|
||||
Set LiteLLM Key in your environment
|
||||
|
||||
```bash
|
||||
LITELLM_LICENSE=""
|
||||
```
|
||||
|
||||
#### Customize Title + Description
|
||||
|
||||
In your environment, set:
|
||||
|
||||
```bash
|
||||
DOCS_TITLE="TotalGPT"
|
||||
DOCS_DESCRIPTION="Sample Company Description"
|
||||
```
|
||||
|
||||
#### Customize Routes
|
||||
|
||||
Hide admin routes from users.
|
||||
|
||||
In your environment, set:
|
||||
|
||||
```bash
|
||||
DOCS_FILTERED="True" # only shows openai routes to user
|
||||
```
|
||||
|
||||
<Image img={require('../../img/custom_swagger.png')} style={{ width: '900px', height: 'auto' }} />
|
||||
|
||||
|
||||
## Enable Blocked User Lists
|
||||
If any call is made to proxy with this user id, it'll be rejected - use this if you want to let users opt-out of ai features
|
||||
|
||||
|
|
@ -417,173 +740,9 @@ curl --location 'http://0.0.0.0:4000/chat/completions' \
|
|||
}
|
||||
'
|
||||
```
|
||||
## Tracking Spend for Custom Tags
|
||||
|
||||
Requirements:
|
||||
## Public Model Hub
|
||||
|
||||
- Virtual Keys & a database should be set up, see [virtual keys](https://docs.litellm.ai/docs/proxy/virtual_keys)
|
||||
Share a public page of available models for users
|
||||
|
||||
### Usage - /chat/completions requests with request tags
|
||||
|
||||
|
||||
<Tabs>
|
||||
|
||||
|
||||
<TabItem value="openai" label="OpenAI Python v1.0.0+">
|
||||
|
||||
Set `extra_body={"metadata": { }}` to `metadata` you want to pass
|
||||
|
||||
```python
|
||||
import openai
|
||||
client = openai.OpenAI(
|
||||
api_key="anything",
|
||||
base_url="http://0.0.0.0:4000"
|
||||
)
|
||||
|
||||
# request sent to model set on litellm proxy, `litellm --model`
|
||||
response = client.chat.completions.create(
|
||||
model="gpt-3.5-turbo",
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "this is a test request, write a short poem"
|
||||
}
|
||||
],
|
||||
extra_body={
|
||||
"metadata": {
|
||||
"tags": ["model-anthropic-claude-v2.1", "app-ishaan-prod"]
|
||||
}
|
||||
}
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="Curl" label="Curl Request">
|
||||
|
||||
Pass `metadata` as part of the request body
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
"metadata": {"tags": ["model-anthropic-claude-v2.1", "app-ishaan-prod"]}
|
||||
}'
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="langchain" label="Langchain">
|
||||
|
||||
```python
|
||||
from langchain.chat_models import ChatOpenAI
|
||||
from langchain.prompts.chat import (
|
||||
ChatPromptTemplate,
|
||||
HumanMessagePromptTemplate,
|
||||
SystemMessagePromptTemplate,
|
||||
)
|
||||
from langchain.schema import HumanMessage, SystemMessage
|
||||
|
||||
chat = ChatOpenAI(
|
||||
openai_api_base="http://0.0.0.0:4000",
|
||||
model = "gpt-3.5-turbo",
|
||||
temperature=0.1,
|
||||
extra_body={
|
||||
"metadata": {
|
||||
"tags": ["model-anthropic-claude-v2.1", "app-ishaan-prod"]
|
||||
}
|
||||
}
|
||||
)
|
||||
|
||||
messages = [
|
||||
SystemMessage(
|
||||
content="You are a helpful assistant that im using to make a test request to."
|
||||
),
|
||||
HumanMessage(
|
||||
content="test from litellm. tell me why it's amazing in 1 sentence"
|
||||
),
|
||||
]
|
||||
response = chat(messages)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
||||
### Viewing Spend per tag
|
||||
|
||||
#### `/spend/tags` Request Format
|
||||
```shell
|
||||
curl -X GET "http://0.0.0.0:4000/spend/tags" \
|
||||
-H "Authorization: Bearer sk-1234"
|
||||
```
|
||||
|
||||
#### `/spend/tags`Response Format
|
||||
```shell
|
||||
[
|
||||
{
|
||||
"individual_request_tag": "model-anthropic-claude-v2.1",
|
||||
"log_count": 6,
|
||||
"total_spend": 0.000672
|
||||
},
|
||||
{
|
||||
"individual_request_tag": "app-ishaan-local",
|
||||
"log_count": 4,
|
||||
"total_spend": 0.000448
|
||||
},
|
||||
{
|
||||
"individual_request_tag": "app-ishaan-prod",
|
||||
"log_count": 2,
|
||||
"total_spend": 0.000224
|
||||
}
|
||||
]
|
||||
|
||||
```
|
||||
|
||||
|
||||
<!-- ## Tracking Spend per Key
|
||||
|
||||
## Tracking Spend per User -->
|
||||
|
||||
## Swagger Docs - Custom Routes + Branding
|
||||
|
||||
:::info
|
||||
|
||||
Requires a LiteLLM Enterprise key to use. Get a free 2-week license [here](https://forms.gle/sTDVprBs18M4V8Le8)
|
||||
|
||||
:::
|
||||
|
||||
Set LiteLLM Key in your environment
|
||||
|
||||
```bash
|
||||
LITELLM_LICENSE=""
|
||||
```
|
||||
|
||||
### Customize Title + Description
|
||||
|
||||
In your environment, set:
|
||||
|
||||
```bash
|
||||
DOCS_TITLE="TotalGPT"
|
||||
DOCS_DESCRIPTION="Sample Company Description"
|
||||
```
|
||||
|
||||
### Customize Routes
|
||||
|
||||
Hide admin routes from users.
|
||||
|
||||
In your environment, set:
|
||||
|
||||
```bash
|
||||
DOCS_FILTERED="True" # only shows openai routes to user
|
||||
```
|
||||
|
||||
<Image img={require('../../img/custom_swagger.png')} style={{ width: '900px', height: 'auto' }} />
|
||||
<Image img={require('../../img/model_hub.png')} style={{ width: '900px', height: 'auto' }}/>
|
||||
|
|
@ -3,22 +3,612 @@ import Tabs from '@theme/Tabs';
|
|||
import TabItem from '@theme/TabItem';
|
||||
|
||||
|
||||
# 🔎 Logging - Custom Callbacks, DataDog, Langfuse, s3 Bucket, Sentry, OpenTelemetry, Athina, Azure Content-Safety
|
||||
# 🪢 Logging - Langfuse, OpenTelemetry, Custom Callbacks, DataDog, s3 Bucket, Sentry, Athina, Azure Content-Safety
|
||||
|
||||
Log Proxy Input, Output, Exceptions using Custom Callbacks, Langfuse, OpenTelemetry, LangFuse, DynamoDB, s3 Bucket
|
||||
Log Proxy Input, Output, Exceptions using Langfuse, OpenTelemetry, Custom Callbacks, DataDog, DynamoDB, s3 Bucket
|
||||
|
||||
- [Logging to Langfuse](#logging-proxy-inputoutput---langfuse)
|
||||
- [Logging with OpenTelemetry (OpenTelemetry)](#logging-proxy-inputoutput-in-opentelemetry-format)
|
||||
- [Async Custom Callbacks](#custom-callback-class-async)
|
||||
- [Async Custom Callback APIs](#custom-callback-apis-async)
|
||||
- [Logging to Langfuse](#logging-proxy-inputoutput---langfuse)
|
||||
- [Logging to OpenMeter](#logging-proxy-inputoutput---langfuse)
|
||||
- [Logging to s3 Buckets](#logging-proxy-inputoutput---s3-buckets)
|
||||
- [Logging to DataDog](#logging-proxy-inputoutput---datadog)
|
||||
- [Logging to DynamoDB](#logging-proxy-inputoutput---dynamodb)
|
||||
- [Logging to Sentry](#logging-proxy-inputoutput---sentry)
|
||||
- [Logging to Traceloop (OpenTelemetry)](#logging-proxy-inputoutput-traceloop-opentelemetry)
|
||||
- [Logging to Athina](#logging-proxy-inputoutput-athina)
|
||||
- [(BETA) Moderation with Azure Content-Safety](#moderation-with-azure-content-safety)
|
||||
|
||||
## Logging Proxy Input/Output - Langfuse
|
||||
We will use the `--config` to set `litellm.success_callback = ["langfuse"]` this will log all successfull LLM calls to langfuse. Make sure to set `LANGFUSE_PUBLIC_KEY` and `LANGFUSE_SECRET_KEY` in your environment
|
||||
|
||||
**Step 1** Install langfuse
|
||||
|
||||
```shell
|
||||
pip install langfuse>=2.0.0
|
||||
```
|
||||
|
||||
**Step 2**: Create a `config.yaml` file and set `litellm_settings`: `success_callback`
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-3.5-turbo
|
||||
litellm_params:
|
||||
model: gpt-3.5-turbo
|
||||
litellm_settings:
|
||||
success_callback: ["langfuse"]
|
||||
```
|
||||
|
||||
**Step 3**: Set required env variables for logging to langfuse
|
||||
```shell
|
||||
export LANGFUSE_PUBLIC_KEY="pk_kk"
|
||||
export LANGFUSE_SECRET_KEY="sk_ss"
|
||||
# Optional, defaults to https://cloud.langfuse.com
|
||||
export LANGFUSE_HOST="https://xxx.langfuse.com"
|
||||
```
|
||||
|
||||
**Step 4**: Start the proxy, make a test request
|
||||
|
||||
Start proxy
|
||||
```shell
|
||||
litellm --config config.yaml --debug
|
||||
```
|
||||
|
||||
Test Request
|
||||
```
|
||||
litellm --test
|
||||
```
|
||||
|
||||
Expected output on Langfuse
|
||||
|
||||
<Image img={require('../../img/langfuse_small.png')} />
|
||||
|
||||
### Logging Metadata to Langfuse
|
||||
|
||||
|
||||
<Tabs>
|
||||
|
||||
<TabItem value="Curl" label="Curl Request">
|
||||
|
||||
Pass `metadata` as part of the request body
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"generation_name": "ishaan-test-generation",
|
||||
"generation_id": "gen-id22",
|
||||
"trace_id": "trace-id22",
|
||||
"trace_user_id": "user-id2"
|
||||
}
|
||||
}'
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="openai" label="OpenAI v1.0.0+">
|
||||
|
||||
Set `extra_body={"metadata": { }}` to `metadata` you want to pass
|
||||
|
||||
```python
|
||||
import openai
|
||||
client = openai.OpenAI(
|
||||
api_key="anything",
|
||||
base_url="http://0.0.0.0:4000"
|
||||
)
|
||||
|
||||
# request sent to model set on litellm proxy, `litellm --model`
|
||||
response = client.chat.completions.create(
|
||||
model="gpt-3.5-turbo",
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "this is a test request, write a short poem"
|
||||
}
|
||||
],
|
||||
extra_body={
|
||||
"metadata": {
|
||||
"generation_name": "ishaan-generation-openai-client",
|
||||
"generation_id": "openai-client-gen-id22",
|
||||
"trace_id": "openai-client-trace-id22",
|
||||
"trace_user_id": "openai-client-user-id2"
|
||||
}
|
||||
}
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="langchain" label="Langchain">
|
||||
|
||||
```python
|
||||
from langchain.chat_models import ChatOpenAI
|
||||
from langchain.prompts.chat import (
|
||||
ChatPromptTemplate,
|
||||
HumanMessagePromptTemplate,
|
||||
SystemMessagePromptTemplate,
|
||||
)
|
||||
from langchain.schema import HumanMessage, SystemMessage
|
||||
|
||||
chat = ChatOpenAI(
|
||||
openai_api_base="http://0.0.0.0:4000",
|
||||
model = "gpt-3.5-turbo",
|
||||
temperature=0.1,
|
||||
extra_body={
|
||||
"metadata": {
|
||||
"generation_name": "ishaan-generation-langchain-client",
|
||||
"generation_id": "langchain-client-gen-id22",
|
||||
"trace_id": "langchain-client-trace-id22",
|
||||
"trace_user_id": "langchain-client-user-id2"
|
||||
}
|
||||
}
|
||||
)
|
||||
|
||||
messages = [
|
||||
SystemMessage(
|
||||
content="You are a helpful assistant that im using to make a test request to."
|
||||
),
|
||||
HumanMessage(
|
||||
content="test from litellm. tell me why it's amazing in 1 sentence"
|
||||
),
|
||||
]
|
||||
response = chat(messages)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
||||
### Team based Logging to Langfuse
|
||||
|
||||
**Example:**
|
||||
|
||||
This config would send langfuse logs to 2 different langfuse projects, based on the team id
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
default_team_settings:
|
||||
- team_id: my-secret-project
|
||||
success_callback: ["langfuse"]
|
||||
langfuse_public_key: os.environ/LANGFUSE_PUB_KEY_1 # Project 1
|
||||
langfuse_secret: os.environ/LANGFUSE_PRIVATE_KEY_1 # Project 1
|
||||
- team_id: ishaans-secret-project
|
||||
success_callback: ["langfuse"]
|
||||
langfuse_public_key: os.environ/LANGFUSE_PUB_KEY_2 # Project 2
|
||||
langfuse_secret: os.environ/LANGFUSE_SECRET_2 # Project 2
|
||||
```
|
||||
|
||||
Now, when you [generate keys](./virtual_keys.md) for this team-id
|
||||
|
||||
```bash
|
||||
curl -X POST 'http://0.0.0.0:4000/key/generate' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-d '{"team_id": "ishaans-secret-project"}'
|
||||
```
|
||||
|
||||
All requests made with these keys will log data to their team-specific logging.
|
||||
|
||||
### Redacting Messages, Response Content from Langfuse Logging
|
||||
|
||||
Set `litellm.turn_off_message_logging=True` This will prevent the messages and responses from being logged to langfuse, but request metadata will still be logged.
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-3.5-turbo
|
||||
litellm_params:
|
||||
model: gpt-3.5-turbo
|
||||
litellm_settings:
|
||||
success_callback: ["langfuse"]
|
||||
turn_off_message_logging: True
|
||||
```
|
||||
|
||||
### 🔧 Debugging - Viewing RAW CURL sent from LiteLLM to provider
|
||||
|
||||
Use this when you want to view the RAW curl request sent from LiteLLM to the LLM API
|
||||
|
||||
<Tabs>
|
||||
|
||||
<TabItem value="Curl" label="Curl Request">
|
||||
|
||||
Pass `metadata` as part of the request body
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"log_raw_request": true
|
||||
}
|
||||
}'
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="openai" label="OpenAI v1.0.0+">
|
||||
|
||||
Set `extra_body={"metadata": {"log_raw_request": True }}` to `metadata` you want to pass
|
||||
|
||||
```python
|
||||
import openai
|
||||
client = openai.OpenAI(
|
||||
api_key="anything",
|
||||
base_url="http://0.0.0.0:4000"
|
||||
)
|
||||
|
||||
# request sent to model set on litellm proxy, `litellm --model`
|
||||
response = client.chat.completions.create(
|
||||
model="gpt-3.5-turbo",
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "this is a test request, write a short poem"
|
||||
}
|
||||
],
|
||||
extra_body={
|
||||
"metadata": {
|
||||
"log_raw_request": True
|
||||
}
|
||||
}
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="langchain" label="Langchain">
|
||||
|
||||
```python
|
||||
from langchain.chat_models import ChatOpenAI
|
||||
from langchain.prompts.chat import (
|
||||
ChatPromptTemplate,
|
||||
HumanMessagePromptTemplate,
|
||||
SystemMessagePromptTemplate,
|
||||
)
|
||||
from langchain.schema import HumanMessage, SystemMessage
|
||||
|
||||
chat = ChatOpenAI(
|
||||
openai_api_base="http://0.0.0.0:4000",
|
||||
model = "gpt-3.5-turbo",
|
||||
temperature=0.1,
|
||||
extra_body={
|
||||
"metadata": {
|
||||
"log_raw_request": True
|
||||
}
|
||||
}
|
||||
)
|
||||
|
||||
messages = [
|
||||
SystemMessage(
|
||||
content="You are a helpful assistant that im using to make a test request to."
|
||||
),
|
||||
HumanMessage(
|
||||
content="test from litellm. tell me why it's amazing in 1 sentence"
|
||||
),
|
||||
]
|
||||
response = chat(messages)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
**Expected Output on Langfuse**
|
||||
|
||||
You will see `raw_request` in your Langfuse Metadata. This is the RAW CURL command sent from LiteLLM to your LLM API provider
|
||||
|
||||
<Image img={require('../../img/debug_langfuse.png')} />
|
||||
|
||||
|
||||
## Logging Proxy Input/Output in OpenTelemetry format
|
||||
|
||||
:::info
|
||||
|
||||
[Optional] Customize OTEL Service Name and OTEL TRACER NAME by setting the following variables in your environment
|
||||
|
||||
```shell
|
||||
OTEL_TRACER_NAME=<your-trace-name> # default="litellm"
|
||||
OTEL_SERVICE_NAME=<your-service-name>` # default="litellm"
|
||||
```
|
||||
|
||||
:::
|
||||
|
||||
<Tabs>
|
||||
|
||||
|
||||
<TabItem value="Console Exporter" label="Log to console">
|
||||
|
||||
|
||||
**Step 1:** Set callbacks and env vars
|
||||
|
||||
Add the following to your env
|
||||
|
||||
```shell
|
||||
OTEL_EXPORTER="console"
|
||||
```
|
||||
|
||||
Add `otel` as a callback on your `litellm_config.yaml`
|
||||
|
||||
```shell
|
||||
litellm_settings:
|
||||
callbacks: ["otel"]
|
||||
```
|
||||
|
||||
|
||||
**Step 2**: Start the proxy, make a test request
|
||||
|
||||
Start proxy
|
||||
|
||||
```shell
|
||||
litellm --config config.yaml --detailed_debug
|
||||
```
|
||||
|
||||
Test Request
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data ' {
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
**Step 3**: **Expect to see the following logged on your server logs / console**
|
||||
|
||||
This is the Span from OTEL Logging
|
||||
|
||||
```json
|
||||
{
|
||||
"name": "litellm-acompletion",
|
||||
"context": {
|
||||
"trace_id": "0x8d354e2346060032703637a0843b20a3",
|
||||
"span_id": "0xd8d3476a2eb12724",
|
||||
"trace_state": "[]"
|
||||
},
|
||||
"kind": "SpanKind.INTERNAL",
|
||||
"parent_id": null,
|
||||
"start_time": "2024-06-04T19:46:56.415888Z",
|
||||
"end_time": "2024-06-04T19:46:56.790278Z",
|
||||
"status": {
|
||||
"status_code": "OK"
|
||||
},
|
||||
"attributes": {
|
||||
"model": "llama3-8b-8192"
|
||||
},
|
||||
"events": [],
|
||||
"links": [],
|
||||
"resource": {
|
||||
"attributes": {
|
||||
"service.name": "litellm"
|
||||
},
|
||||
"schema_url": ""
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
|
||||
<TabItem value="Honeycomb" label="Log to Honeycomb">
|
||||
|
||||
#### Quick Start - Log to Honeycomb
|
||||
|
||||
**Step 1:** Set callbacks and env vars
|
||||
|
||||
Add the following to your env
|
||||
|
||||
```shell
|
||||
OTEL_EXPORTER="otlp_http"
|
||||
OTEL_ENDPOINT="https://api.honeycomb.io/v1/traces"
|
||||
OTEL_HEADERS="x-honeycomb-team=<your-api-key>"
|
||||
```
|
||||
|
||||
Add `otel` as a callback on your `litellm_config.yaml`
|
||||
|
||||
```shell
|
||||
litellm_settings:
|
||||
callbacks: ["otel"]
|
||||
```
|
||||
|
||||
|
||||
**Step 2**: Start the proxy, make a test request
|
||||
|
||||
Start proxy
|
||||
|
||||
```shell
|
||||
litellm --config config.yaml --detailed_debug
|
||||
```
|
||||
|
||||
Test Request
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data ' {
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
|
||||
</TabItem>
|
||||
|
||||
|
||||
<TabItem value="otel-col" label="Log to OTEL HTTP Collector">
|
||||
|
||||
#### Quick Start - Log to OTEL Collector
|
||||
|
||||
**Step 1:** Set callbacks and env vars
|
||||
|
||||
Add the following to your env
|
||||
|
||||
```shell
|
||||
OTEL_EXPORTER="otlp_http"
|
||||
OTEL_ENDPOINT="http:/0.0.0.0:4317"
|
||||
OTEL_HEADERS="x-honeycomb-team=<your-api-key>" # Optional
|
||||
```
|
||||
|
||||
Add `otel` as a callback on your `litellm_config.yaml`
|
||||
|
||||
```shell
|
||||
litellm_settings:
|
||||
callbacks: ["otel"]
|
||||
```
|
||||
|
||||
|
||||
**Step 2**: Start the proxy, make a test request
|
||||
|
||||
Start proxy
|
||||
|
||||
```shell
|
||||
litellm --config config.yaml --detailed_debug
|
||||
```
|
||||
|
||||
Test Request
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data ' {
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
|
||||
<TabItem value="otel-col-grpc" label="Log to OTEL GRPC Collector">
|
||||
|
||||
#### Quick Start - Log to OTEL GRPC Collector
|
||||
|
||||
**Step 1:** Set callbacks and env vars
|
||||
|
||||
Add the following to your env
|
||||
|
||||
```shell
|
||||
OTEL_EXPORTER="otlp_grpc"
|
||||
OTEL_ENDPOINT="http:/0.0.0.0:4317"
|
||||
OTEL_HEADERS="x-honeycomb-team=<your-api-key>" # Optional
|
||||
```
|
||||
|
||||
Add `otel` as a callback on your `litellm_config.yaml`
|
||||
|
||||
```shell
|
||||
litellm_settings:
|
||||
callbacks: ["otel"]
|
||||
```
|
||||
|
||||
|
||||
**Step 2**: Start the proxy, make a test request
|
||||
|
||||
Start proxy
|
||||
|
||||
```shell
|
||||
litellm --config config.yaml --detailed_debug
|
||||
```
|
||||
|
||||
Test Request
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data ' {
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="traceloop" label="Log to Traceloop Cloud">
|
||||
|
||||
#### Quick Start - Log to Traceloop
|
||||
|
||||
**Step 1:** Install the `traceloop-sdk` SDK
|
||||
|
||||
```shell
|
||||
pip install traceloop-sdk==0.21.2
|
||||
```
|
||||
|
||||
**Step 2:** Add `traceloop` as a success_callback
|
||||
|
||||
```shell
|
||||
litellm_settings:
|
||||
success_callback: ["traceloop"]
|
||||
|
||||
environment_variables:
|
||||
TRACELOOP_API_KEY: "XXXXX"
|
||||
```
|
||||
|
||||
|
||||
**Step 3**: Start the proxy, make a test request
|
||||
|
||||
Start proxy
|
||||
|
||||
```shell
|
||||
litellm --config config.yaml --detailed_debug
|
||||
```
|
||||
|
||||
Test Request
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data ' {
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
</Tabs>
|
||||
|
||||
** 🎉 Expect to see this trace logged in your OTEL collector**
|
||||
|
||||
|
||||
|
||||
|
||||
## Custom Callback Class [Async]
|
||||
Use this when you want to run custom callbacks in `python`
|
||||
|
||||
|
|
@ -402,197 +992,6 @@ litellm_settings:
|
|||
|
||||
Start the LiteLLM Proxy and make a test request to verify the logs reached your callback API
|
||||
|
||||
## Logging Proxy Input/Output - Langfuse
|
||||
We will use the `--config` to set `litellm.success_callback = ["langfuse"]` this will log all successfull LLM calls to langfuse. Make sure to set `LANGFUSE_PUBLIC_KEY` and `LANGFUSE_SECRET_KEY` in your environment
|
||||
|
||||
**Step 1** Install langfuse
|
||||
|
||||
```shell
|
||||
pip install langfuse>=2.0.0
|
||||
```
|
||||
|
||||
**Step 2**: Create a `config.yaml` file and set `litellm_settings`: `success_callback`
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-3.5-turbo
|
||||
litellm_params:
|
||||
model: gpt-3.5-turbo
|
||||
litellm_settings:
|
||||
success_callback: ["langfuse"]
|
||||
```
|
||||
|
||||
**Step 3**: Set required env variables for logging to langfuse
|
||||
```shell
|
||||
export LANGFUSE_PUBLIC_KEY="pk_kk"
|
||||
export LANGFUSE_SECRET_KEY="sk_ss
|
||||
```
|
||||
|
||||
**Step 4**: Start the proxy, make a test request
|
||||
|
||||
Start proxy
|
||||
```shell
|
||||
litellm --config config.yaml --debug
|
||||
```
|
||||
|
||||
Test Request
|
||||
```
|
||||
litellm --test
|
||||
```
|
||||
|
||||
Expected output on Langfuse
|
||||
|
||||
<Image img={require('../../img/langfuse_small.png')} />
|
||||
|
||||
### Logging Metadata to Langfuse
|
||||
|
||||
|
||||
<Tabs>
|
||||
|
||||
<TabItem value="Curl" label="Curl Request">
|
||||
|
||||
Pass `metadata` as part of the request body
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"generation_name": "ishaan-test-generation",
|
||||
"generation_id": "gen-id22",
|
||||
"trace_id": "trace-id22",
|
||||
"trace_user_id": "user-id2"
|
||||
}
|
||||
}'
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="openai" label="OpenAI v1.0.0+">
|
||||
|
||||
Set `extra_body={"metadata": { }}` to `metadata` you want to pass
|
||||
|
||||
```python
|
||||
import openai
|
||||
client = openai.OpenAI(
|
||||
api_key="anything",
|
||||
base_url="http://0.0.0.0:4000"
|
||||
)
|
||||
|
||||
# request sent to model set on litellm proxy, `litellm --model`
|
||||
response = client.chat.completions.create(
|
||||
model="gpt-3.5-turbo",
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "this is a test request, write a short poem"
|
||||
}
|
||||
],
|
||||
extra_body={
|
||||
"metadata": {
|
||||
"generation_name": "ishaan-generation-openai-client",
|
||||
"generation_id": "openai-client-gen-id22",
|
||||
"trace_id": "openai-client-trace-id22",
|
||||
"trace_user_id": "openai-client-user-id2"
|
||||
}
|
||||
}
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="langchain" label="Langchain">
|
||||
|
||||
```python
|
||||
from langchain.chat_models import ChatOpenAI
|
||||
from langchain.prompts.chat import (
|
||||
ChatPromptTemplate,
|
||||
HumanMessagePromptTemplate,
|
||||
SystemMessagePromptTemplate,
|
||||
)
|
||||
from langchain.schema import HumanMessage, SystemMessage
|
||||
|
||||
chat = ChatOpenAI(
|
||||
openai_api_base="http://0.0.0.0:4000",
|
||||
model = "gpt-3.5-turbo",
|
||||
temperature=0.1,
|
||||
extra_body={
|
||||
"metadata": {
|
||||
"generation_name": "ishaan-generation-langchain-client",
|
||||
"generation_id": "langchain-client-gen-id22",
|
||||
"trace_id": "langchain-client-trace-id22",
|
||||
"trace_user_id": "langchain-client-user-id2"
|
||||
}
|
||||
}
|
||||
)
|
||||
|
||||
messages = [
|
||||
SystemMessage(
|
||||
content="You are a helpful assistant that im using to make a test request to."
|
||||
),
|
||||
HumanMessage(
|
||||
content="test from litellm. tell me why it's amazing in 1 sentence"
|
||||
),
|
||||
]
|
||||
response = chat(messages)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
|
||||
### Team based Logging to Langfuse
|
||||
|
||||
**Example:**
|
||||
|
||||
This config would send langfuse logs to 2 different langfuse projects, based on the team id
|
||||
|
||||
```yaml
|
||||
litellm_settings:
|
||||
default_team_settings:
|
||||
- team_id: my-secret-project
|
||||
success_callback: ["langfuse"]
|
||||
langfuse_public_key: os.environ/LANGFUSE_PUB_KEY_1 # Project 1
|
||||
langfuse_secret: os.environ/LANGFUSE_PRIVATE_KEY_1 # Project 1
|
||||
- team_id: ishaans-secret-project
|
||||
success_callback: ["langfuse"]
|
||||
langfuse_public_key: os.environ/LANGFUSE_PUB_KEY_2 # Project 2
|
||||
langfuse_secret: os.environ/LANGFUSE_SECRET_2 # Project 2
|
||||
```
|
||||
|
||||
Now, when you [generate keys](./virtual_keys.md) for this team-id
|
||||
|
||||
```bash
|
||||
curl -X POST 'http://0.0.0.0:4000/key/generate' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-d '{"team_id": "ishaans-secret-project"}'
|
||||
```
|
||||
|
||||
All requests made with these keys will log data to their team-specific logging.
|
||||
|
||||
### Redacting Messages, Response Content from Langfuse Logging
|
||||
|
||||
Set `litellm.turn_off_message_logging=True` This will prevent the messages and responses from being logged to langfuse, but request metadata will still be logged.
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-3.5-turbo
|
||||
litellm_params:
|
||||
model: gpt-3.5-turbo
|
||||
litellm_settings:
|
||||
success_callback: ["langfuse"]
|
||||
turn_off_message_logging: True
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Logging Proxy Cost + Usage - OpenMeter
|
||||
|
||||
Bill customers according to their LLM API usage with [OpenMeter](../observability/openmeter.md)
|
||||
|
|
@ -915,86 +1314,6 @@ Test Request
|
|||
litellm --test
|
||||
```
|
||||
|
||||
## Logging Proxy Input/Output in OpenTelemetry format using Traceloop's OpenLLMetry
|
||||
|
||||
[OpenLLMetry](https://github.com/traceloop/openllmetry) _(built and maintained by Traceloop)_ is a set of extensions
|
||||
built on top of [OpenTelemetry](https://opentelemetry.io/) that gives you complete observability over your LLM
|
||||
application. Because it uses OpenTelemetry under the
|
||||
hood, [it can be connected to various observability solutions](https://www.traceloop.com/docs/openllmetry/integrations/introduction)
|
||||
like:
|
||||
|
||||
* [Traceloop](https://www.traceloop.com/docs/openllmetry/integrations/traceloop)
|
||||
* [Axiom](https://www.traceloop.com/docs/openllmetry/integrations/axiom)
|
||||
* [Azure Application Insights](https://www.traceloop.com/docs/openllmetry/integrations/azure)
|
||||
* [Datadog](https://www.traceloop.com/docs/openllmetry/integrations/datadog)
|
||||
* [Dynatrace](https://www.traceloop.com/docs/openllmetry/integrations/dynatrace)
|
||||
* [Grafana Tempo](https://www.traceloop.com/docs/openllmetry/integrations/grafana)
|
||||
* [Honeycomb](https://www.traceloop.com/docs/openllmetry/integrations/honeycomb)
|
||||
* [HyperDX](https://www.traceloop.com/docs/openllmetry/integrations/hyperdx)
|
||||
* [Instana](https://www.traceloop.com/docs/openllmetry/integrations/instana)
|
||||
* [New Relic](https://www.traceloop.com/docs/openllmetry/integrations/newrelic)
|
||||
* [OpenTelemetry Collector](https://www.traceloop.com/docs/openllmetry/integrations/otel-collector)
|
||||
* [Service Now Cloud Observability](https://www.traceloop.com/docs/openllmetry/integrations/service-now)
|
||||
* [Sentry](https://www.traceloop.com/docs/openllmetry/integrations/sentry)
|
||||
* [SigNoz](https://www.traceloop.com/docs/openllmetry/integrations/signoz)
|
||||
* [Splunk](https://www.traceloop.com/docs/openllmetry/integrations/splunk)
|
||||
|
||||
We will use the `--config` to set `litellm.success_callback = ["traceloop"]` to achieve this, steps are listed below.
|
||||
|
||||
**Step 1:** Install the SDK
|
||||
|
||||
```shell
|
||||
pip install traceloop-sdk
|
||||
```
|
||||
|
||||
**Step 2:** Configure Environment Variable for trace exporting
|
||||
|
||||
You will need to configure where to export your traces. Environment variables will control this, example: For Traceloop
|
||||
you should use `TRACELOOP_API_KEY`, whereas for Datadog you use `TRACELOOP_BASE_URL`. For more
|
||||
visit [the Integrations Catalog](https://www.traceloop.com/docs/openllmetry/integrations/introduction).
|
||||
|
||||
If you are using Datadog as the observability solutions then you can set `TRACELOOP_BASE_URL` as:
|
||||
|
||||
```shell
|
||||
TRACELOOP_BASE_URL=http://<datadog-agent-hostname>:4318
|
||||
```
|
||||
|
||||
**Step 3**: Create a `config.yaml` file and set `litellm_settings`: `success_callback`
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-3.5-turbo
|
||||
litellm_params:
|
||||
model: gpt-3.5-turbo
|
||||
api_key: my-fake-key # replace api_key with actual key
|
||||
litellm_settings:
|
||||
success_callback: [ "traceloop" ]
|
||||
```
|
||||
|
||||
**Step 4**: Start the proxy, make a test request
|
||||
|
||||
Start proxy
|
||||
|
||||
```shell
|
||||
litellm --config config.yaml --debug
|
||||
```
|
||||
|
||||
Test Request
|
||||
|
||||
```
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data ' {
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
## Logging Proxy Input/Output Athina
|
||||
|
||||
[Athina](https://athina.ai/) allows you to log LLM Input/Output for monitoring, analytics, and observability.
|
||||
|
|
|
|||
99
docs/my-website/docs/proxy/multiple_admins.md
Normal file
|
|
@ -0,0 +1,99 @@
|
|||
# ✨ Attribute Management changes to Users
|
||||
|
||||
Call management endpoints on behalf of a user. (Useful when connecting proxy to your development platform).
|
||||
|
||||
|
||||
:::tip
|
||||
|
||||
Requires Enterprise License, Get in touch with us [here](https://calendly.com/d/4mp-gd3-k5k/litellm-1-1-onboarding-chat)
|
||||
|
||||
:::
|
||||
|
||||
## 1. Switch on audit Logs
|
||||
Add `store_audit_logs` to your litellm config.yaml and then start the proxy
|
||||
```shell
|
||||
litellm_settings:
|
||||
store_audit_logs: true
|
||||
```
|
||||
|
||||
## 2. Set `LiteLLM-Changed-By` in request headers
|
||||
|
||||
Set the 'user_id' in request headers, when calling a management endpoint. [View Full List](https://litellm-api.up.railway.app/#/team%20management).
|
||||
|
||||
- Update Team budget with master key.
|
||||
- Attribute change to 'krrish@berri.ai'.
|
||||
|
||||
**👉 Key change:** Passing `-H 'LiteLLM-Changed-By: krrish@berri.ai'`
|
||||
|
||||
```shell
|
||||
curl -X POST 'http://0.0.0.0:4000/team/update' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-H 'LiteLLM-Changed-By: krrish@berri.ai' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-d '{
|
||||
"team_id" : "8bf18b11-7f52-4717-8e1f-7c65f9d01e52",
|
||||
"max_budget": 2000
|
||||
}'
|
||||
```
|
||||
|
||||
## 3. Emitted Audit Log
|
||||
|
||||
```bash
|
||||
{
|
||||
"id": "bd136c28-edd0-4cb6-b963-f35464cf6f5a",
|
||||
"updated_at": "2024-06-08 23:41:14.793",
|
||||
"changed_by": "krrish@berri.ai", # 👈 CHANGED BY
|
||||
"changed_by_api_key": "88dc28d0f030c55ed4ab77ed8faf098196cb1c05df778539800c9f1243fe6b4b",
|
||||
"action": "updated",
|
||||
"table_name": "LiteLLM_TeamTable",
|
||||
"object_id": "8bf18b11-7f52-4717-8e1f-7c65f9d01e52",
|
||||
"before_value": {
|
||||
"spend": 0,
|
||||
"max_budget": 0,
|
||||
},
|
||||
"updated_values": {
|
||||
"team_id": "8bf18b11-7f52-4717-8e1f-7c65f9d01e52",
|
||||
"max_budget": 2000 # 👈 CHANGED TO
|
||||
},
|
||||
}
|
||||
```
|
||||
|
||||
## API SPEC of Audit Log
|
||||
|
||||
|
||||
### `id`
|
||||
- **Type:** `String`
|
||||
- **Description:** This is the unique identifier for each audit log entry. It is automatically generated as a UUID (Universally Unique Identifier) by default.
|
||||
|
||||
### `updated_at`
|
||||
- **Type:** `DateTime`
|
||||
- **Description:** This field stores the timestamp of when the audit log entry was created or updated. It is automatically set to the current date and time by default.
|
||||
|
||||
### `changed_by`
|
||||
- **Type:** `String`
|
||||
- **Description:** The `user_id` that performed the audited action. If `LiteLLM-Changed-By` Header is passed then `changed_by=<value passed for LiteLLM-Changed-By header>`
|
||||
|
||||
### `changed_by_api_key`
|
||||
- **Type:** `String`
|
||||
- **Description:** This field stores the hashed API key that was used to perform the audited action. If left blank, it defaults to an empty string.
|
||||
|
||||
### `action`
|
||||
- **Type:** `String`
|
||||
- **Description:** The type of action that was performed. One of "create", "update", or "delete".
|
||||
|
||||
### `table_name`
|
||||
- **Type:** `String`
|
||||
- **Description:** This field stores the name of the table that was affected by the audited action. It can be one of the following values: `LiteLLM_TeamTable`, `LiteLLM_UserTable`, `LiteLLM_VerificationToken`
|
||||
|
||||
|
||||
### `object_id`
|
||||
- **Type:** `String`
|
||||
- **Description:** This field stores the ID of the object that was affected by the audited action. It can be the key ID, team ID, user ID
|
||||
|
||||
### `before_value`
|
||||
- **Type:** `Json?`
|
||||
- **Description:** This field stores the value of the row before the audited action was performed. It is optional and can be null.
|
||||
|
||||
### `updated_values`
|
||||
- **Type:** `Json?`
|
||||
- **Description:** This field stores the values of the row that were updated after the audited action was performed
|
||||
|
|
@ -21,6 +21,7 @@ general_settings:
|
|||
|
||||
litellm_settings:
|
||||
set_verbose: False # Switch off Debug Logging, ensure your logs do not have any debugging on
|
||||
json_logs: true # Get debug logs in json format
|
||||
```
|
||||
|
||||
Set slack webhook url in your env
|
||||
|
|
@ -28,6 +29,11 @@ Set slack webhook url in your env
|
|||
export SLACK_WEBHOOK_URL="https://hooks.slack.com/services/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"
|
||||
```
|
||||
|
||||
Turn off FASTAPI's default info logs
|
||||
```bash
|
||||
export LITELLM_LOG="ERROR"
|
||||
```
|
||||
|
||||
:::info
|
||||
|
||||
Need Help or want dedicated support ? Talk to a founder [here]: (https://calendly.com/d/4mp-gd3-k5k/litellm-1-1-onboarding-chat)
|
||||
|
|
|
|||
|
|
@ -24,6 +24,15 @@ $ litellm --model huggingface/bigcode/starcoder
|
|||
#INFO: Proxy running on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
|
||||
:::info
|
||||
|
||||
Run with `--detailed_debug` if you need detailed debug logs
|
||||
|
||||
```shell
|
||||
$ litellm --model huggingface/bigcode/starcoder --detailed_debug
|
||||
:::
|
||||
|
||||
### Test
|
||||
In a new shell, run, this will make an `openai.chat.completions` request. Ensure you're using openai v1.0.0+
|
||||
```shell
|
||||
|
|
|
|||
|
|
@ -2,18 +2,13 @@ import Image from '@theme/IdealImage';
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# 🔥 Fallbacks, Retries, Timeouts, Load Balancing
|
||||
# 🔥 Load Balancing, Fallbacks, Retries, Timeouts
|
||||
|
||||
Retry call with multiple instances of the same model.
|
||||
|
||||
If a call fails after num_retries, fall back to another model group.
|
||||
|
||||
If the error is a context window exceeded error, fall back to a larger model group (if given).
|
||||
|
||||
[**See Code**](https://github.com/BerriAI/litellm/blob/main/litellm/router.py)
|
||||
- Quick Start [load balancing](#test---load-balancing)
|
||||
- Quick Start [client side fallbacks](#test---client-side-fallbacks)
|
||||
|
||||
## Quick Start - Load Balancing
|
||||
### Step 1 - Set deployments on config
|
||||
#### Step 1 - Set deployments on config
|
||||
|
||||
**Example config below**. Here requests with `model=gpt-3.5-turbo` will be routed across multiple instances of `azure/gpt-3.5-turbo`
|
||||
```yaml
|
||||
|
|
@ -38,50 +33,214 @@ model_list:
|
|||
rpm: 1440
|
||||
```
|
||||
|
||||
### Step 2: Start Proxy with config
|
||||
#### Step 2: Start Proxy with config
|
||||
|
||||
```shell
|
||||
$ litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
### Step 3: Use proxy - Call a model group [Load Balancing]
|
||||
Curl Command
|
||||
### Test - Load Balancing
|
||||
|
||||
Here requests with model=gpt-3.5-turbo will be routed across multiple instances of azure/gpt-3.5-turbo
|
||||
|
||||
👉 Key Change: `model="gpt-3.5-turbo"`
|
||||
|
||||
**Check the `model_id` in Response Headers to make sure the requests are being load balanced**
|
||||
|
||||
<Tabs>
|
||||
|
||||
<TabItem value="openai" label="OpenAI Python v1.0.0+">
|
||||
|
||||
```python
|
||||
import openai
|
||||
client = openai.OpenAI(
|
||||
api_key="anything",
|
||||
base_url="http://0.0.0.0:4000"
|
||||
)
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="gpt-3.5-turbo",
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "this is a test request, write a short poem"
|
||||
}
|
||||
]
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="Curl" label="Curl Request">
|
||||
|
||||
Pass `metadata` as part of the request body
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data ' {
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
}
|
||||
'
|
||||
]
|
||||
}'
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="langchain" label="Langchain">
|
||||
|
||||
```python
|
||||
from langchain.chat_models import ChatOpenAI
|
||||
from langchain.prompts.chat import (
|
||||
ChatPromptTemplate,
|
||||
HumanMessagePromptTemplate,
|
||||
SystemMessagePromptTemplate,
|
||||
)
|
||||
from langchain.schema import HumanMessage, SystemMessage
|
||||
import os
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "anything"
|
||||
|
||||
chat = ChatOpenAI(
|
||||
openai_api_base="http://0.0.0.0:4000",
|
||||
model="gpt-3.5-turbo",
|
||||
)
|
||||
|
||||
messages = [
|
||||
SystemMessage(
|
||||
content="You are a helpful assistant that im using to make a test request to."
|
||||
),
|
||||
HumanMessage(
|
||||
content="test from litellm. tell me why it's amazing in 1 sentence"
|
||||
),
|
||||
]
|
||||
response = chat(messages)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
### Usage - Call a specific model deployment
|
||||
If you want to call a specific model defined in the `config.yaml`, you can call the `litellm_params: model`
|
||||
</TabItem>
|
||||
|
||||
</Tabs>
|
||||
|
||||
|
||||
### Test - Client Side Fallbacks
|
||||
In this request the following will occur:
|
||||
1. The request to `model="zephyr-beta"` will fail
|
||||
2. litellm proxy will loop through all the model_groups specified in `fallbacks=["gpt-3.5-turbo"]`
|
||||
3. The request to `model="gpt-3.5-turbo"` will succeed and the client making the request will get a response from gpt-3.5-turbo
|
||||
|
||||
👉 Key Change: `"fallbacks": ["gpt-3.5-turbo"]`
|
||||
|
||||
<Tabs>
|
||||
|
||||
<TabItem value="openai" label="OpenAI Python v1.0.0+">
|
||||
|
||||
```python
|
||||
import openai
|
||||
client = openai.OpenAI(
|
||||
api_key="anything",
|
||||
base_url="http://0.0.0.0:4000"
|
||||
)
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="zephyr-beta",
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "this is a test request, write a short poem"
|
||||
}
|
||||
],
|
||||
extra_body={
|
||||
"fallbacks": ["gpt-3.5-turbo"]
|
||||
}
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="Curl" label="Curl Request">
|
||||
|
||||
Pass `metadata` as part of the request body
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "zephyr-beta"",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
"fallbacks": ["gpt-3.5-turbo"]
|
||||
}'
|
||||
```
|
||||
</TabItem>
|
||||
<TabItem value="langchain" label="Langchain">
|
||||
|
||||
```python
|
||||
from langchain.chat_models import ChatOpenAI
|
||||
from langchain.prompts.chat import (
|
||||
ChatPromptTemplate,
|
||||
HumanMessagePromptTemplate,
|
||||
SystemMessagePromptTemplate,
|
||||
)
|
||||
from langchain.schema import HumanMessage, SystemMessage
|
||||
import os
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "anything"
|
||||
|
||||
chat = ChatOpenAI(
|
||||
openai_api_base="http://0.0.0.0:4000",
|
||||
model="zephyr-beta",
|
||||
extra_body={
|
||||
"fallbacks": ["gpt-3.5-turbo"]
|
||||
}
|
||||
)
|
||||
|
||||
messages = [
|
||||
SystemMessage(
|
||||
content="You are a helpful assistant that im using to make a test request to."
|
||||
),
|
||||
HumanMessage(
|
||||
content="test from litellm. tell me why it's amazing in 1 sentence"
|
||||
),
|
||||
]
|
||||
response = chat(messages)
|
||||
|
||||
print(response)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
</Tabs>
|
||||
|
||||
|
||||
|
||||
<!--
|
||||
### Test it!
|
||||
|
||||
In this example it will call `azure/gpt-turbo-small-ca`. Defined in the config on Step 1
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data ' {
|
||||
"model": "azure/gpt-turbo-small-ca",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
}
|
||||
'
|
||||
```
|
||||
--header 'Content-Type: application/json' \
|
||||
--data-raw '{
|
||||
"model": "zephyr-beta", # 👈 MODEL NAME to fallback from
|
||||
"messages": [
|
||||
{"role": "user", "content": "what color is red"}
|
||||
],
|
||||
"mock_testing_fallbacks": true
|
||||
}'
|
||||
``` -->
|
||||
|
||||
## Fallbacks + Retries + Timeouts + Cooldowns
|
||||
## Advanced
|
||||
### Fallbacks + Retries + Timeouts + Cooldowns
|
||||
|
||||
**Set via config**
|
||||
```yaml
|
||||
|
|
@ -114,44 +273,7 @@ litellm_settings:
|
|||
context_window_fallbacks: [{"zephyr-beta": ["gpt-3.5-turbo-16k"]}, {"gpt-3.5-turbo": ["gpt-3.5-turbo-16k"]}] # fallback to gpt-3.5-turbo-16k if context window error
|
||||
allowed_fails: 3 # cooldown model if it fails > 1 call in a minute.
|
||||
```
|
||||
|
||||
**Set dynamically**
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data ' {
|
||||
"model": "zephyr-beta",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
"fallbacks": [{"zephyr-beta": ["gpt-3.5-turbo"]}],
|
||||
"context_window_fallbacks": [{"zephyr-beta": ["gpt-3.5-turbo"]}],
|
||||
"num_retries": 2,
|
||||
"timeout": 10
|
||||
}
|
||||
'
|
||||
```
|
||||
|
||||
### Test it!
|
||||
|
||||
|
||||
```bash
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data-raw '{
|
||||
"model": "zephyr-beta", # 👈 MODEL NAME to fallback from
|
||||
"messages": [
|
||||
{"role": "user", "content": "what color is red"}
|
||||
],
|
||||
"mock_testing_fallbacks": true
|
||||
}'
|
||||
```
|
||||
|
||||
## Advanced - Context Window Fallbacks (Pre-Call Checks + Fallbacks)
|
||||
### Context Window Fallbacks (Pre-Call Checks + Fallbacks)
|
||||
|
||||
**Before call is made** check if a call is within model context window with **`enable_pre_call_checks: true`**.
|
||||
|
||||
|
|
@ -287,7 +409,7 @@ print(response)
|
|||
</Tabs>
|
||||
|
||||
|
||||
## Advanced - EU-Region Filtering (Pre-Call Checks)
|
||||
### EU-Region Filtering (Pre-Call Checks)
|
||||
|
||||
**Before call is made** check if a call is within model context window with **`enable_pre_call_checks: true`**.
|
||||
|
||||
|
|
@ -350,7 +472,7 @@ print(response)
|
|||
print(f"response.headers.get('x-litellm-model-api-base')")
|
||||
```
|
||||
|
||||
## Advanced - Custom Timeouts, Stream Timeouts - Per Model
|
||||
### Custom Timeouts, Stream Timeouts - Per Model
|
||||
For each model you can set `timeout` & `stream_timeout` under `litellm_params`
|
||||
```yaml
|
||||
model_list:
|
||||
|
|
@ -379,7 +501,7 @@ $ litellm --config /path/to/config.yaml
|
|||
```
|
||||
|
||||
|
||||
## Advanced - Setting Dynamic Timeouts - Per Request
|
||||
### Setting Dynamic Timeouts - Per Request
|
||||
|
||||
LiteLLM Proxy supports setting a `timeout` per request
|
||||
|
||||
|
|
|
|||
126
docs/my-website/docs/proxy/self_serve.md
Normal file
|
|
@ -0,0 +1,126 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# 🤗 UI - Self-Serve
|
||||
|
||||
Allow users to creat their own keys on [Proxy UI](./ui.md).
|
||||
|
||||
1. Add user with permissions to a team on proxy
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI">
|
||||
|
||||
Go to `Internal Users` -> `+New User`
|
||||
|
||||
<Image img={require('../../img/add_internal_user.png')} style={{ width: '800px', height: 'auto' }} />
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
Create a new Internal User on LiteLLM and assign them the role `internal_user`.
|
||||
|
||||
```bash
|
||||
curl -X POST '<PROXY_BASE_URL>/user/new' \
|
||||
-H 'Authorization: Bearer <PROXY_MASTER_KEY>' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-D '{
|
||||
"user_email": "krrishdholakia@gmail.com",
|
||||
"user_role": "internal_user" # 👈 THIS ALLOWS USER TO CREATE/VIEW/DELETE THEIR OWN KEYS + SEE THEIR SPEND
|
||||
}'
|
||||
```
|
||||
|
||||
Expected Response
|
||||
|
||||
```bash
|
||||
{
|
||||
"user_id": "e9d45c7c-b20b-4ff8-ae76-3f479a7b1d7d", 👈 USE IN STEP 2
|
||||
"user_email": "<YOUR_USERS_EMAIL>",
|
||||
"user_role": "internal_user",
|
||||
...
|
||||
}
|
||||
```
|
||||
|
||||
Here's the available UI roles for a LiteLLM Internal User:
|
||||
|
||||
Admin Roles:
|
||||
- `proxy_admin`: admin over the platform
|
||||
- `proxy_admin_viewer`: can login, view all keys, view all spend. **Cannot** create/delete keys, add new users.
|
||||
|
||||
Internal User Roles:
|
||||
- `internal_user`: can login, view/create/delete their own keys, view their spend. **Cannot** add new users.
|
||||
- `internal_user_viewer`: can login, view their own keys, view their own spend. **Cannot** create/delete keys, add new users.
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
2. Share invitation link with user
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="ui" label="UI">
|
||||
|
||||
Copy the invitation link with the user
|
||||
|
||||
<Image img={require('../../img/invitation_link.png')} style={{ width: '800px', height: 'auto' }} />
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="api" label="API">
|
||||
|
||||
```bash
|
||||
curl -X POST '<PROXY_BASE_URL>/invitation/new' \
|
||||
-H 'Authorization: Bearer <PROXY_MASTER_KEY>' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-D '{
|
||||
"user_id": "e9d45c7c-b20b..." # 👈 USER ID FROM STEP 1
|
||||
}'
|
||||
```
|
||||
|
||||
Expected Response
|
||||
|
||||
```bash
|
||||
{
|
||||
"id": "a2f0918f-43b0-4770-a664-96ddd192966e",
|
||||
"user_id": "e9d45c7c-b20b..",
|
||||
"is_accepted": false,
|
||||
"accepted_at": null,
|
||||
"expires_at": "2024-06-13T00:02:16.454000Z", # 👈 VALID FOR 7d
|
||||
"created_at": "2024-06-06T00:02:16.454000Z",
|
||||
"created_by": "116544810872468347480",
|
||||
"updated_at": "2024-06-06T00:02:16.454000Z",
|
||||
"updated_by": "116544810872468347480"
|
||||
}
|
||||
```
|
||||
|
||||
Invitation Link:
|
||||
|
||||
```bash
|
||||
http://0.0.0.0:4000/ui/onboarding?id=a2f0918f-43b0-4770-a664-96ddd192966e
|
||||
|
||||
# <YOUR_PROXY_BASE_URL>/ui/onboarding?id=<id>
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
:::info
|
||||
|
||||
Use [Email Notifications](./email.md) to email users onboarding links
|
||||
|
||||
:::
|
||||
|
||||
3. User logs in via email + password auth
|
||||
|
||||
<Image img={require('../../img/ui_clean_login.png')} style={{ width: '500px', height: 'auto' }} />
|
||||
|
||||
|
||||
|
||||
:::info
|
||||
|
||||
LiteLLM Enterprise: Enable [SSO login](./ui.md#setup-ssoauth-for-ui)
|
||||
|
||||
:::
|
||||
|
||||
4. User can now create their own keys
|
||||
|
||||
|
||||
<Image img={require('../../img/ui_self_serve_create_key.png')} style={{ width: '800px', height: 'auto' }} />
|
||||
|
|
@ -2,10 +2,9 @@ import Image from '@theme/IdealImage';
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# [BETA] Proxy UI
|
||||
### **Create + delete keys through a UI**
|
||||
# [BETA] UI - Admin
|
||||
|
||||
[Let users create their own keys](#setup-ssoauth-for-ui)
|
||||
Create keys, track spend, add models without worrying about the config / CRUD endpoints.
|
||||
|
||||
:::info
|
||||
|
||||
|
|
|
|||
|
|
@ -63,7 +63,7 @@ You can:
|
|||
- Add budgets to Teams
|
||||
|
||||
|
||||
#### **Add budgets to users**
|
||||
#### **Add budgets to teams**
|
||||
```shell
|
||||
curl --location 'http://localhost:4000/team/new' \
|
||||
--header 'Authorization: Bearer <your-master-key>' \
|
||||
|
|
@ -102,6 +102,22 @@ curl --location 'http://localhost:4000/team/new' \
|
|||
"budget_reset_at": null
|
||||
}
|
||||
```
|
||||
|
||||
#### **Add budget duration to teams**
|
||||
|
||||
`budget_duration`: Budget is reset at the end of specified duration. If not set, budget is never reset. You can set duration as seconds ("30s"), minutes ("30m"), hours ("30h"), days ("30d").
|
||||
|
||||
```
|
||||
curl 'http://0.0.0.0:4000/team/new' \
|
||||
--header 'Authorization: Bearer <your-master-key>' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data-raw '{
|
||||
"team_alias": "my-new-team_4",
|
||||
"members_with_roles": [{"role": "admin", "user_id": "5c4a0aa3-a1e1-43dc-bd87-3c2da8382a3a"}],
|
||||
"budget_duration": 10s,
|
||||
}'
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
<TabItem value="per-team-member" label="For Team Members">
|
||||
|
||||
|
|
|
|||
|
|
@ -713,26 +713,43 @@ response = router.completion(model="gpt-3.5-turbo", messages=messages)
|
|||
print(f"response: {response}")
|
||||
```
|
||||
|
||||
#### Retries based on Error Type
|
||||
### [Advanced]: Custom Retries, Cooldowns based on Error Type
|
||||
|
||||
Use `RetryPolicy` if you want to set a `num_retries` based on the Exception receieved
|
||||
- Use `RetryPolicy` if you want to set a `num_retries` based on the Exception receieved
|
||||
- Use `AllowedFailsPolicy` to set a custom number of `allowed_fails`/minute before cooling down a deployment
|
||||
|
||||
Example:
|
||||
- 4 retries for `ContentPolicyViolationError`
|
||||
- 0 retries for `RateLimitErrors`
|
||||
|
||||
```python
|
||||
retry_policy = RetryPolicy(
|
||||
ContentPolicyViolationErrorRetries=3, # run 3 retries for ContentPolicyViolationErrors
|
||||
AuthenticationErrorRetries=0, # run 0 retries for AuthenticationErrorRetries
|
||||
)
|
||||
|
||||
allowed_fails_policy = AllowedFailsPolicy(
|
||||
ContentPolicyViolationErrorAllowedFails=1000, # Allow 1000 ContentPolicyViolationError before cooling down a deployment
|
||||
RateLimitErrorAllowedFails=100, # Allow 100 RateLimitErrors before cooling down a deployment
|
||||
)
|
||||
```
|
||||
|
||||
Example Usage
|
||||
|
||||
```python
|
||||
from litellm.router import RetryPolicy
|
||||
from litellm.router import RetryPolicy, AllowedFailsPolicy
|
||||
|
||||
retry_policy = RetryPolicy(
|
||||
ContentPolicyViolationErrorRetries=3, # run 3 retries for ContentPolicyViolationErrors
|
||||
AuthenticationErrorRetries=0, # run 0 retries for AuthenticationErrorRetries
|
||||
ContentPolicyViolationErrorRetries=3, # run 3 retries for ContentPolicyViolationErrors
|
||||
AuthenticationErrorRetries=0, # run 0 retries for AuthenticationErrorRetries
|
||||
BadRequestErrorRetries=1,
|
||||
TimeoutErrorRetries=2,
|
||||
RateLimitErrorRetries=3,
|
||||
)
|
||||
|
||||
allowed_fails_policy = AllowedFailsPolicy(
|
||||
ContentPolicyViolationErrorAllowedFails=1000, # Allow 1000 ContentPolicyViolationError before cooling down a deployment
|
||||
RateLimitErrorAllowedFails=100, # Allow 100 RateLimitErrors before cooling down a deployment
|
||||
)
|
||||
|
||||
router = litellm.Router(
|
||||
model_list=[
|
||||
{
|
||||
|
|
@ -755,6 +772,7 @@ router = litellm.Router(
|
|||
},
|
||||
],
|
||||
retry_policy=retry_policy,
|
||||
allowed_fails_policy=allowed_fails_policy,
|
||||
)
|
||||
|
||||
response = await router.acompletion(
|
||||
|
|
|
|||
|
|
@ -22,9 +22,7 @@ Prioritize LLM API requests in high-traffic.
|
|||
## Quick Start
|
||||
|
||||
```python
|
||||
from litellm import Scheduler, FlowItem, Router
|
||||
|
||||
scheduler = Scheduler()
|
||||
from litellm import Router
|
||||
|
||||
router = Router(
|
||||
model_list=[
|
||||
|
|
@ -39,53 +37,17 @@ router = Router(
|
|||
],
|
||||
timeout=2, # timeout request if takes > 2s
|
||||
routing_strategy="usage-based-routing-v2",
|
||||
polling_interval=0.03 # poll queue every 3ms if no healthy deployments
|
||||
)
|
||||
|
||||
scheduler.update_variables(llm_router=router)
|
||||
|
||||
### 🚨 IMPORTANT ###
|
||||
|
||||
item = FlowItem(
|
||||
priority=0, # 👈 SET PRIORITY FOR REQUEST
|
||||
request_id=str(uuid.uuid4()), # 👈 SET REQUEST ID
|
||||
model_name="gpt-3.5-turbo" # 👈 SAME as 'Router'
|
||||
)
|
||||
|
||||
### [fin] IMPORTANT ###
|
||||
|
||||
## ADDS REQUEST TO QUEUE ##
|
||||
await scheduler.add_request(request=item)
|
||||
|
||||
## POLL QUEUE
|
||||
default_timeout = router.timeout
|
||||
end_time = time.time() + default_timeout
|
||||
poll_interval = 0.03 # poll every 3ms
|
||||
curr_time = time.time()
|
||||
|
||||
make_request = False
|
||||
|
||||
while curr_time < end_time:
|
||||
make_request = await scheduler.poll( ## POLL QUEUE ## - returns 'True' if there's healthy deployments OR if request is at top of queue
|
||||
id=item.request_id, model_name=item.model_name
|
||||
try:
|
||||
_response = await router.schedule_acompletion( # 👈 ADDS TO QUEUE + POLLS + MAKES CALL
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "Hey!"}],
|
||||
priority=0, # 👈 LOWER IS BETTER
|
||||
)
|
||||
if make_request: ## IF TRUE -> MAKE REQUEST
|
||||
break
|
||||
else: ## ELSE -> loop till default_timeout
|
||||
await asyncio.sleep(poll_interval)
|
||||
curr_time = time.time()
|
||||
|
||||
if make_request:
|
||||
try:
|
||||
_response = await router.acompletion(
|
||||
model=item.model_name,
|
||||
messages=[{"role": "user", "content": "Hey!"}],
|
||||
)
|
||||
except Exception as e:
|
||||
print("{}, {}, {}".format(item.priority, item.request_id, "Error occurred"))
|
||||
|
||||
print("{}, {}, {}".format(item.priority, item.request_id, time.time()))
|
||||
|
||||
print("didn't make request")
|
||||
except Exception as e:
|
||||
print("didn't make request")
|
||||
```
|
||||
|
||||
## LiteLLM Proxy
|
||||
|
|
@ -138,4 +100,76 @@ print(response)
|
|||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
</Tabs>
|
||||
|
||||
## Advanced - Redis Caching
|
||||
|
||||
Use redis caching to do request prioritization across multiple instances of LiteLLM.
|
||||
|
||||
### SDK
|
||||
```python
|
||||
from litellm import Router
|
||||
|
||||
router = Router(
|
||||
model_list=[
|
||||
{
|
||||
"model_name": "gpt-3.5-turbo",
|
||||
"litellm_params": {
|
||||
"model": "gpt-3.5-turbo",
|
||||
"mock_response": "Hello world this is Macintosh!", # fakes the LLM API call
|
||||
"rpm": 1,
|
||||
},
|
||||
},
|
||||
],
|
||||
### REDIS PARAMS ###
|
||||
redis_host=os.environ["REDIS_HOST"],
|
||||
redis_password=os.environ["REDIS_PASSWORD"],
|
||||
redis_port=os.environ["REDIS_PORT"],
|
||||
)
|
||||
|
||||
try:
|
||||
_response = await router.schedule_acompletion( # 👈 ADDS TO QUEUE + POLLS + MAKES CALL
|
||||
model="gpt-3.5-turbo",
|
||||
messages=[{"role": "user", "content": "Hey!"}],
|
||||
priority=0, # 👈 LOWER IS BETTER
|
||||
)
|
||||
except Exception as e:
|
||||
print("didn't make request")
|
||||
```
|
||||
|
||||
### PROXY
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gpt-3.5-turbo-fake-model
|
||||
litellm_params:
|
||||
model: gpt-3.5-turbo
|
||||
mock_response: "hello world!"
|
||||
api_key: my-good-key
|
||||
|
||||
router_settings:
|
||||
redis_host; os.environ/REDIS_HOST
|
||||
redis_password: os.environ/REDIS_PASSWORD
|
||||
redis_port: os.environ/REDIS_PORT
|
||||
```
|
||||
|
||||
```bash
|
||||
$ litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000s
|
||||
```
|
||||
|
||||
```bash
|
||||
curl -X POST 'http://localhost:4000/queue/chat/completions' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-D '{
|
||||
"model": "gpt-3.5-turbo-fake-model",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what is the meaning of the universe? 1234"
|
||||
}],
|
||||
"priority": 0 👈 SET VALUE HERE
|
||||
}'
|
||||
```
|
||||
|
|
@ -1,11 +1,31 @@
|
|||
# Secret Manager
|
||||
LiteLLM supports reading secrets from Azure Key Vault and Infisical
|
||||
|
||||
- AWS Key Managemenet Service
|
||||
- AWS Secret Manager
|
||||
- [Azure Key Vault](#azure-key-vault)
|
||||
- Google Key Management Service
|
||||
- [Infisical Secret Manager](#infisical-secret-manager)
|
||||
- [.env Files](#env-files)
|
||||
|
||||
## AWS Key Management Service
|
||||
|
||||
Use AWS KMS to storing a hashed copy of your Proxy Master Key in the environment.
|
||||
|
||||
```bash
|
||||
export LITELLM_MASTER_KEY="djZ9xjVaZ..." # 👈 ENCRYPTED KEY
|
||||
export AWS_REGION_NAME="us-west-2"
|
||||
```
|
||||
|
||||
```yaml
|
||||
general_settings:
|
||||
key_management_system: "aws_kms"
|
||||
key_management_settings:
|
||||
hosted_keys: ["LITELLM_MASTER_KEY"] # 👈 WHICH KEYS ARE STORED ON KMS
|
||||
```
|
||||
|
||||
[**See Decryption Code**](https://github.com/BerriAI/litellm/blob/a2da2a8f168d45648b61279d4795d647d94f90c9/litellm/utils.py#L10182)
|
||||
|
||||
## AWS Secret Manager
|
||||
|
||||
Store your proxy keys in AWS Secret Manager.
|
||||
|
|
|
|||
87
docs/my-website/docs/text_to_speech.md
Normal file
|
|
@ -0,0 +1,87 @@
|
|||
# Text to Speech
|
||||
|
||||
## Quick Start
|
||||
|
||||
```python
|
||||
from pathlib import Path
|
||||
from litellm import speech
|
||||
import os
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "sk-.."
|
||||
|
||||
speech_file_path = Path(__file__).parent / "speech.mp3"
|
||||
response = speech(
|
||||
model="openai/tts-1",
|
||||
voice="alloy",
|
||||
input="the quick brown fox jumped over the lazy dogs",
|
||||
api_base=None,
|
||||
api_key=None,
|
||||
organization=None,
|
||||
project=None,
|
||||
max_retries=1,
|
||||
timeout=600,
|
||||
client=None,
|
||||
optional_params={},
|
||||
)
|
||||
response.stream_to_file(speech_file_path)
|
||||
```
|
||||
|
||||
## Async Usage
|
||||
|
||||
```python
|
||||
from litellm import aspeech
|
||||
from pathlib import Path
|
||||
import os, asyncio
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "sk-.."
|
||||
|
||||
async def test_async_speech():
|
||||
speech_file_path = Path(__file__).parent / "speech.mp3"
|
||||
response = await litellm.aspeech(
|
||||
model="openai/tts-1",
|
||||
voice="alloy",
|
||||
input="the quick brown fox jumped over the lazy dogs",
|
||||
api_base=None,
|
||||
api_key=None,
|
||||
organization=None,
|
||||
project=None,
|
||||
max_retries=1,
|
||||
timeout=600,
|
||||
client=None,
|
||||
optional_params={},
|
||||
)
|
||||
response.stream_to_file(speech_file_path)
|
||||
|
||||
asyncio.run(test_async_speech())
|
||||
```
|
||||
|
||||
## Proxy Usage
|
||||
|
||||
LiteLLM provides an openai-compatible `/audio/speech` endpoint for Text-to-speech calls.
|
||||
|
||||
```bash
|
||||
curl http://0.0.0.0:4000/v1/audio/speech \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "tts-1",
|
||||
"input": "The quick brown fox jumped over the lazy dog.",
|
||||
"voice": "alloy"
|
||||
}' \
|
||||
--output speech.mp3
|
||||
```
|
||||
|
||||
**Setup**
|
||||
|
||||
```bash
|
||||
- model_name: tts
|
||||
litellm_params:
|
||||
model: openai/tts-1
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
```
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
|
@ -1,8 +1,8 @@
|
|||
# Using Fine-Tuned gpt-3.5-turbo
|
||||
LiteLLM allows you to call `completion` with your fine-tuned gpt-3.5-turbo models
|
||||
If you're trying to create your custom finetuned gpt-3.5-turbo model following along on this tutorial: https://platform.openai.com/docs/guides/fine-tuning/preparing-your-dataset
|
||||
If you're trying to create your custom fine-tuned gpt-3.5-turbo model following along on this tutorial: https://platform.openai.com/docs/guides/fine-tuning/preparing-your-dataset
|
||||
|
||||
Once you've created your fine tuned model, you can call it with `litellm.completion()`
|
||||
Once you've created your fine-tuned model, you can call it with `litellm.completion()`
|
||||
|
||||
## Usage
|
||||
```python
|
||||
|
|
|
|||
BIN
docs/my-website/img/add_internal_user.png
Normal file

|
After Width: | Height: | Size: 145 KiB |
BIN
docs/my-website/img/admin_ui_spend.png
Normal file

|
After Width: | Height: | Size: 176 KiB |
BIN
docs/my-website/img/debug_langfuse.png
Normal file

|
After Width: | Height: | Size: 130 KiB |
BIN
docs/my-website/img/invitation_link.png
Normal file

|
After Width: | Height: | Size: 133 KiB |
BIN
docs/my-website/img/model_hub.png
Normal file

|
After Width: | Height: | Size: 253 KiB |
BIN
docs/my-website/img/ui_clean_login.png
Normal file

|
After Width: | Height: | Size: 132 KiB |
BIN
docs/my-website/img/ui_self_serve_create_key.png
Normal file

|
After Width: | Height: | Size: 179 KiB |
6
docs/my-website/package-lock.json
generated
|
|
@ -5975,9 +5975,9 @@
|
|||
}
|
||||
},
|
||||
"node_modules/caniuse-lite": {
|
||||
"version": "1.0.30001519",
|
||||
"resolved": "https://registry.npmjs.org/caniuse-lite/-/caniuse-lite-1.0.30001519.tgz",
|
||||
"integrity": "sha512-0QHgqR+Jv4bxHMp8kZ1Kn8CH55OikjKJ6JmKkZYP1F3D7w+lnFXF70nG5eNfsZS89jadi5Ywy5UCSKLAglIRkg==",
|
||||
"version": "1.0.30001629",
|
||||
"resolved": "https://registry.npmjs.org/caniuse-lite/-/caniuse-lite-1.0.30001629.tgz",
|
||||
"integrity": "sha512-c3dl911slnQhmxUIT4HhYzT7wnBK/XYpGnYLOj4nJBaRiw52Ibe7YxlDaAeRECvA786zCuExhxIUJ2K7nHMrBw==",
|
||||
"funding": [
|
||||
{
|
||||
"type": "opencollective",
|
||||
|
|
|
|||
|
|
@ -36,24 +36,26 @@ const sidebars = {
|
|||
label: "📖 All Endpoints (Swagger)",
|
||||
href: "https://litellm-api.up.railway.app/",
|
||||
},
|
||||
"proxy/enterprise",
|
||||
"proxy/demo",
|
||||
"proxy/configs",
|
||||
"proxy/reliability",
|
||||
"proxy/cost_tracking",
|
||||
"proxy/self_serve",
|
||||
"proxy/users",
|
||||
"proxy/customers",
|
||||
"proxy/billing",
|
||||
"proxy/user_keys",
|
||||
"proxy/enterprise",
|
||||
"proxy/virtual_keys",
|
||||
"proxy/alerting",
|
||||
{
|
||||
type: "category",
|
||||
label: "Logging",
|
||||
label: "🪢 Logging",
|
||||
items: ["proxy/logging", "proxy/streaming_logging"],
|
||||
},
|
||||
"proxy/ui",
|
||||
"proxy/email",
|
||||
"proxy/multiple_admins",
|
||||
"proxy/team_based_routing",
|
||||
"proxy/customer_routing",
|
||||
"proxy/token_auth",
|
||||
|
|
@ -100,13 +102,16 @@ const sidebars = {
|
|||
},
|
||||
{
|
||||
type: "category",
|
||||
label: "Embedding(), Moderation(), Image Generation(), Audio Transcriptions()",
|
||||
label: "Embedding(), Image Generation(), Assistants(), Moderation(), Audio Transcriptions(), TTS(), Batches()",
|
||||
items: [
|
||||
"embedding/supported_embedding",
|
||||
"embedding/async_embedding",
|
||||
"embedding/moderation",
|
||||
"image_generation",
|
||||
"audio_transcription"
|
||||
"audio_transcription",
|
||||
"text_to_speech",
|
||||
"assistants",
|
||||
"batches",
|
||||
],
|
||||
},
|
||||
{
|
||||
|
|
@ -250,6 +255,7 @@ const sidebars = {
|
|||
"projects/GPT Migrate",
|
||||
"projects/YiVal",
|
||||
"projects/LiteLLM Proxy",
|
||||
"projects/llm_cord",
|
||||
],
|
||||
},
|
||||
],
|
||||
|
|
|
|||
|
|
@ -18,10 +18,6 @@ async def log_event(request: Request):
|
|||
|
||||
return {"message": "Request received successfully"}
|
||||
except Exception as e:
|
||||
print(f"Error processing request: {str(e)}")
|
||||
import traceback
|
||||
|
||||
traceback.print_exc()
|
||||
raise HTTPException(status_code=500, detail="Internal Server Error")
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -120,6 +120,5 @@ class GenericAPILogger:
|
|||
)
|
||||
return response
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.debug(f"Generic - {str(e)}\n{traceback.format_exc()}")
|
||||
verbose_logger.error(f"Generic - {str(e)}\n{traceback.format_exc()}")
|
||||
pass
|
||||
|
|
|
|||
|
|
@ -82,7 +82,7 @@ class _ENTERPRISE_BannedKeywords(CustomLogger):
|
|||
except HTTPException as e:
|
||||
raise e
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_proxy_logger.error(traceback.format_exc())
|
||||
|
||||
async def async_post_call_success_hook(
|
||||
self,
|
||||
|
|
|
|||
|
|
@ -118,4 +118,4 @@ class _ENTERPRISE_BlockedUserList(CustomLogger):
|
|||
except HTTPException as e:
|
||||
raise e
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_proxy_logger.error(traceback.format_exc())
|
||||
|
|
|
|||
|
|
@ -92,7 +92,7 @@ class _ENTERPRISE_LLMGuard(CustomLogger):
|
|||
},
|
||||
)
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_proxy_logger.error(traceback.format_exc())
|
||||
raise e
|
||||
|
||||
def should_proceed(self, user_api_key_dict: UserAPIKeyAuth, data: dict) -> bool:
|
||||
|
|
|
|||
|
|
@ -1,5 +1,7 @@
|
|||
# Enterprise Proxy Util Endpoints
|
||||
from typing import Optional, List
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.proxy.proxy_server import PrismaClient, HTTPException
|
||||
import collections
|
||||
from datetime import datetime
|
||||
|
||||
|
|
@ -19,27 +21,76 @@ async def get_spend_by_tags(start_date=None, end_date=None, prisma_client=None):
|
|||
return response
|
||||
|
||||
|
||||
async def ui_get_spend_by_tags(start_date: str, end_date: str, prisma_client):
|
||||
|
||||
sql_query = """
|
||||
SELECT
|
||||
jsonb_array_elements_text(request_tags) AS individual_request_tag,
|
||||
DATE(s."startTime") AS spend_date,
|
||||
COUNT(*) AS log_count,
|
||||
SUM(spend) AS total_spend
|
||||
FROM "LiteLLM_SpendLogs" s
|
||||
WHERE
|
||||
DATE(s."startTime") >= $1::date
|
||||
AND DATE(s."startTime") <= $2::date
|
||||
GROUP BY individual_request_tag, spend_date
|
||||
ORDER BY spend_date
|
||||
LIMIT 100;
|
||||
async def ui_get_spend_by_tags(
|
||||
start_date: str,
|
||||
end_date: str,
|
||||
prisma_client: Optional[PrismaClient] = None,
|
||||
tags_str: Optional[str] = None,
|
||||
):
|
||||
"""
|
||||
response = await prisma_client.db.query_raw(
|
||||
sql_query,
|
||||
start_date,
|
||||
end_date,
|
||||
)
|
||||
Should cover 2 cases:
|
||||
1. When user is getting spend for all_tags. "all_tags" in tags_list
|
||||
2. When user is getting spend for specific tags.
|
||||
"""
|
||||
|
||||
# tags_str is a list of strings csv of tags
|
||||
# tags_str = tag1,tag2,tag3
|
||||
# convert to list if it's not None
|
||||
tags_list: Optional[List[str]] = None
|
||||
if tags_str is not None and len(tags_str) > 0:
|
||||
tags_list = tags_str.split(",")
|
||||
|
||||
if prisma_client is None:
|
||||
raise HTTPException(status_code=500, detail={"error": "No db connected"})
|
||||
|
||||
response = None
|
||||
if tags_list is None or (isinstance(tags_list, list) and "all-tags" in tags_list):
|
||||
# Get spend for all tags
|
||||
sql_query = """
|
||||
SELECT
|
||||
jsonb_array_elements_text(request_tags) AS individual_request_tag,
|
||||
DATE(s."startTime") AS spend_date,
|
||||
COUNT(*) AS log_count,
|
||||
SUM(spend) AS total_spend
|
||||
FROM "LiteLLM_SpendLogs" s
|
||||
WHERE
|
||||
DATE(s."startTime") >= $1::date
|
||||
AND DATE(s."startTime") <= $2::date
|
||||
GROUP BY individual_request_tag, spend_date
|
||||
ORDER BY total_spend DESC;
|
||||
"""
|
||||
response = await prisma_client.db.query_raw(
|
||||
sql_query,
|
||||
start_date,
|
||||
end_date,
|
||||
)
|
||||
else:
|
||||
# filter by tags list
|
||||
sql_query = """
|
||||
SELECT
|
||||
individual_request_tag,
|
||||
COUNT(*) AS log_count,
|
||||
SUM(spend) AS total_spend
|
||||
FROM (
|
||||
SELECT
|
||||
jsonb_array_elements_text(request_tags) AS individual_request_tag,
|
||||
DATE(s."startTime") AS spend_date,
|
||||
spend
|
||||
FROM "LiteLLM_SpendLogs" s
|
||||
WHERE
|
||||
DATE(s."startTime") >= $1::date
|
||||
AND DATE(s."startTime") <= $2::date
|
||||
) AS subquery
|
||||
WHERE individual_request_tag = ANY($3::text[])
|
||||
GROUP BY individual_request_tag
|
||||
ORDER BY total_spend DESC;
|
||||
"""
|
||||
response = await prisma_client.db.query_raw(
|
||||
sql_query,
|
||||
start_date,
|
||||
end_date,
|
||||
tags_list,
|
||||
)
|
||||
|
||||
# print("tags - spend")
|
||||
# print(response)
|
||||
|
|
|
|||
|
|
@ -5,7 +5,7 @@ warnings.filterwarnings("ignore", message=".*conflict with protected namespace.*
|
|||
### INIT VARIABLES ###
|
||||
import threading, requests, os
|
||||
from typing import Callable, List, Optional, Dict, Union, Any, Literal
|
||||
from litellm.llms.custom_httpx.http_handler import AsyncHTTPHandler
|
||||
from litellm.llms.custom_httpx.http_handler import AsyncHTTPHandler, HTTPHandler
|
||||
from litellm.caching import Cache
|
||||
from litellm._logging import (
|
||||
set_verbose,
|
||||
|
|
@ -60,6 +60,8 @@ _async_failure_callback: List[Callable] = (
|
|||
pre_call_rules: List[Callable] = []
|
||||
post_call_rules: List[Callable] = []
|
||||
turn_off_message_logging: Optional[bool] = False
|
||||
redact_messages_in_exceptions: Optional[bool] = False
|
||||
store_audit_logs = False # Enterprise feature, allow users to see audit logs
|
||||
## end of callbacks #############
|
||||
|
||||
email: Optional[str] = (
|
||||
|
|
@ -102,6 +104,7 @@ common_cloud_provider_auth_params: dict = {
|
|||
}
|
||||
use_client: bool = False
|
||||
ssl_verify: bool = True
|
||||
ssl_certificate: Optional[str] = None
|
||||
disable_streaming_logging: bool = False
|
||||
in_memory_llm_clients_cache: dict = {}
|
||||
### GUARDRAILS ###
|
||||
|
|
@ -214,7 +217,6 @@ add_function_to_prompt: bool = (
|
|||
)
|
||||
client_session: Optional[httpx.Client] = None
|
||||
aclient_session: Optional[httpx.AsyncClient] = None
|
||||
module_level_aclient = AsyncHTTPHandler()
|
||||
model_fallbacks: Optional[List] = None # Deprecated for 'litellm.fallbacks'
|
||||
model_cost_map_url: str = (
|
||||
"https://raw.githubusercontent.com/BerriAI/litellm/main/model_prices_and_context_window.json"
|
||||
|
|
@ -231,6 +233,8 @@ max_user_budget: Optional[float] = None
|
|||
max_end_user_budget: Optional[float] = None
|
||||
#### RELIABILITY ####
|
||||
request_timeout: float = 6000
|
||||
module_level_aclient = AsyncHTTPHandler(timeout=request_timeout)
|
||||
module_level_client = HTTPHandler(timeout=request_timeout)
|
||||
num_retries: Optional[int] = None # per model endpoint
|
||||
default_fallbacks: Optional[List] = None
|
||||
fallbacks: Optional[List] = None
|
||||
|
|
@ -705,6 +709,7 @@ all_embedding_models = (
|
|||
openai_image_generation_models = ["dall-e-2", "dall-e-3"]
|
||||
|
||||
from .timeout import timeout
|
||||
from .cost_calculator import completion_cost
|
||||
from .utils import (
|
||||
client,
|
||||
exception_type,
|
||||
|
|
@ -714,7 +719,6 @@ from .utils import (
|
|||
create_pretrained_tokenizer,
|
||||
create_tokenizer,
|
||||
cost_per_token,
|
||||
completion_cost,
|
||||
supports_function_calling,
|
||||
supports_parallel_function_calling,
|
||||
supports_vision,
|
||||
|
|
@ -764,7 +768,7 @@ from .llms.sagemaker import SagemakerConfig
|
|||
from .llms.ollama import OllamaConfig
|
||||
from .llms.ollama_chat import OllamaChatConfig
|
||||
from .llms.maritalk import MaritTalkConfig
|
||||
from .llms.bedrock_httpx import AmazonCohereChatConfig
|
||||
from .llms.bedrock_httpx import AmazonCohereChatConfig, AmazonConverseConfig
|
||||
from .llms.bedrock import (
|
||||
AmazonTitanConfig,
|
||||
AmazonAI21Config,
|
||||
|
|
@ -782,7 +786,11 @@ from .llms.openai import (
|
|||
MistralConfig,
|
||||
DeepInfraConfig,
|
||||
)
|
||||
from .llms.azure import AzureOpenAIConfig, AzureOpenAIError
|
||||
from .llms.azure import (
|
||||
AzureOpenAIConfig,
|
||||
AzureOpenAIError,
|
||||
AzureOpenAIAssistantsAPIConfig,
|
||||
)
|
||||
from .llms.watsonx import IBMWatsonXAIConfig
|
||||
from .main import * # type: ignore
|
||||
from .integrations import *
|
||||
|
|
@ -802,6 +810,8 @@ from .exceptions import (
|
|||
APIConnectionError,
|
||||
APIResponseValidationError,
|
||||
UnprocessableEntityError,
|
||||
InternalServerError,
|
||||
LITELLM_EXCEPTION_TYPES,
|
||||
)
|
||||
from .budget_manager import BudgetManager
|
||||
from .proxy.proxy_cli import run_server
|
||||
|
|
@ -809,3 +819,4 @@ from .router import Router
|
|||
from .assistants.main import *
|
||||
from .batches.main import *
|
||||
from .scheduler import *
|
||||
from .cost_calculator import response_cost_calculator
|
||||
|
|
|
|||
|
|
@ -1,5 +1,6 @@
|
|||
import logging, os, json
|
||||
from logging import Formatter
|
||||
import traceback
|
||||
|
||||
set_verbose = False
|
||||
json_logs = bool(os.getenv("JSON_LOGS", False))
|
||||
|
|
@ -41,12 +42,19 @@ verbose_logger.addHandler(handler)
|
|||
|
||||
def _turn_on_json():
|
||||
handler = logging.StreamHandler()
|
||||
handler.setLevel(logging.DEBUG)
|
||||
handler.setFormatter(JsonFormatter())
|
||||
|
||||
verbose_router_logger.addHandler(handler)
|
||||
verbose_proxy_logger.addHandler(handler)
|
||||
verbose_logger.addHandler(handler)
|
||||
# Define a list of the loggers to update
|
||||
loggers = [verbose_router_logger, verbose_proxy_logger, verbose_logger]
|
||||
|
||||
# Iterate through each logger and update its handlers
|
||||
for logger in loggers:
|
||||
# Remove all existing handlers
|
||||
for h in logger.handlers[:]:
|
||||
logger.removeHandler(h)
|
||||
|
||||
# Add the new handler
|
||||
logger.addHandler(handler)
|
||||
|
||||
|
||||
def _turn_on_debug():
|
||||
|
|
|
|||
|
|
@ -1,10 +1,18 @@
|
|||
import litellm, traceback
|
||||
from datetime import datetime
|
||||
import litellm
|
||||
from litellm.proxy._types import UserAPIKeyAuth
|
||||
from .types.services import ServiceTypes, ServiceLoggerPayload
|
||||
from .integrations.prometheus_services import PrometheusServicesLogger
|
||||
from .integrations.custom_logger import CustomLogger
|
||||
from datetime import timedelta
|
||||
from typing import Union
|
||||
from typing import Union, Optional, TYPE_CHECKING, Any
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from opentelemetry.trace import Span as _Span
|
||||
|
||||
Span = _Span
|
||||
else:
|
||||
Span = Any
|
||||
|
||||
|
||||
class ServiceLogging(CustomLogger):
|
||||
|
|
@ -40,7 +48,13 @@ class ServiceLogging(CustomLogger):
|
|||
self.mock_testing_sync_failure_hook += 1
|
||||
|
||||
async def async_service_success_hook(
|
||||
self, service: ServiceTypes, duration: float, call_type: str
|
||||
self,
|
||||
service: ServiceTypes,
|
||||
call_type: str,
|
||||
duration: float,
|
||||
parent_otel_span: Optional[Span] = None,
|
||||
start_time: Optional[datetime] = None,
|
||||
end_time: Optional[datetime] = None,
|
||||
):
|
||||
"""
|
||||
- For counting if the redis, postgres call is successful
|
||||
|
|
@ -61,12 +75,25 @@ class ServiceLogging(CustomLogger):
|
|||
payload=payload
|
||||
)
|
||||
|
||||
from litellm.proxy.proxy_server import open_telemetry_logger
|
||||
|
||||
if parent_otel_span is not None and open_telemetry_logger is not None:
|
||||
await open_telemetry_logger.async_service_success_hook(
|
||||
payload=payload,
|
||||
parent_otel_span=parent_otel_span,
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
)
|
||||
|
||||
async def async_service_failure_hook(
|
||||
self,
|
||||
service: ServiceTypes,
|
||||
duration: float,
|
||||
error: Union[str, Exception],
|
||||
call_type: str,
|
||||
parent_otel_span: Optional[Span] = None,
|
||||
start_time: Optional[datetime] = None,
|
||||
end_time: Optional[datetime] = None,
|
||||
):
|
||||
"""
|
||||
- For counting if the redis, postgres call is unsuccessful
|
||||
|
|
@ -95,6 +122,16 @@ class ServiceLogging(CustomLogger):
|
|||
payload=payload
|
||||
)
|
||||
|
||||
from litellm.proxy.proxy_server import open_telemetry_logger
|
||||
|
||||
if parent_otel_span is not None and open_telemetry_logger is not None:
|
||||
await open_telemetry_logger.async_service_failure_hook(
|
||||
payload=payload,
|
||||
parent_otel_span=parent_otel_span,
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
)
|
||||
|
||||
async def async_post_call_failure_hook(
|
||||
self, original_exception: Exception, user_api_key_dict: UserAPIKeyAuth
|
||||
):
|
||||
|
|
|
|||
|
|
@ -4,21 +4,29 @@ from typing import Iterable
|
|||
from functools import partial
|
||||
import os, asyncio, contextvars
|
||||
import litellm
|
||||
from openai import OpenAI, AsyncOpenAI
|
||||
from openai import OpenAI, AsyncOpenAI, AzureOpenAI, AsyncAzureOpenAI
|
||||
from litellm import client
|
||||
from litellm.utils import supports_httpx_timeout, exception_type, get_llm_provider
|
||||
from litellm.utils import (
|
||||
supports_httpx_timeout,
|
||||
exception_type,
|
||||
get_llm_provider,
|
||||
get_secret,
|
||||
)
|
||||
from ..llms.openai import OpenAIAssistantsAPI
|
||||
from ..llms.azure import AzureAssistantsAPI
|
||||
from ..types.llms.openai import *
|
||||
from ..types.router import *
|
||||
from .utils import get_optional_params_add_message
|
||||
|
||||
####### ENVIRONMENT VARIABLES ###################
|
||||
openai_assistants_api = OpenAIAssistantsAPI()
|
||||
azure_assistants_api = AzureAssistantsAPI()
|
||||
|
||||
### ASSISTANTS ###
|
||||
|
||||
|
||||
async def aget_assistants(
|
||||
custom_llm_provider: Literal["openai"],
|
||||
custom_llm_provider: Literal["openai", "azure"],
|
||||
client: Optional[AsyncOpenAI] = None,
|
||||
**kwargs,
|
||||
) -> AsyncCursorPage[Assistant]:
|
||||
|
|
@ -55,12 +63,21 @@ async def aget_assistants(
|
|||
|
||||
|
||||
def get_assistants(
|
||||
custom_llm_provider: Literal["openai"],
|
||||
client: Optional[OpenAI] = None,
|
||||
custom_llm_provider: Literal["openai", "azure"],
|
||||
client: Optional[Any] = None,
|
||||
api_key: Optional[str] = None,
|
||||
api_base: Optional[str] = None,
|
||||
api_version: Optional[str] = None,
|
||||
**kwargs,
|
||||
) -> SyncCursorPage[Assistant]:
|
||||
aget_assistants = kwargs.pop("aget_assistants", None)
|
||||
optional_params = GenericLiteLLMParams(**kwargs)
|
||||
aget_assistants: Optional[bool] = kwargs.pop("aget_assistants", None)
|
||||
if aget_assistants is not None and not isinstance(aget_assistants, bool):
|
||||
raise Exception(
|
||||
"Invalid value passed in for aget_assistants. Only bool or None allowed"
|
||||
)
|
||||
optional_params = GenericLiteLLMParams(
|
||||
api_key=api_key, api_base=api_base, api_version=api_version, **kwargs
|
||||
)
|
||||
|
||||
### TIMEOUT LOGIC ###
|
||||
timeout = optional_params.timeout or kwargs.get("request_timeout", 600) or 600
|
||||
|
|
@ -99,6 +116,7 @@ def get_assistants(
|
|||
or litellm.openai_key
|
||||
or os.getenv("OPENAI_API_KEY")
|
||||
)
|
||||
|
||||
response = openai_assistants_api.get_assistants(
|
||||
api_base=api_base,
|
||||
api_key=api_key,
|
||||
|
|
@ -106,7 +124,43 @@ def get_assistants(
|
|||
max_retries=optional_params.max_retries,
|
||||
organization=organization,
|
||||
client=client,
|
||||
aget_assistants=aget_assistants,
|
||||
aget_assistants=aget_assistants, # type: ignore
|
||||
) # type: ignore
|
||||
elif custom_llm_provider == "azure":
|
||||
api_base = (
|
||||
optional_params.api_base or litellm.api_base or get_secret("AZURE_API_BASE")
|
||||
) # type: ignore
|
||||
|
||||
api_version = (
|
||||
optional_params.api_version
|
||||
or litellm.api_version
|
||||
or get_secret("AZURE_API_VERSION")
|
||||
) # type: ignore
|
||||
|
||||
api_key = (
|
||||
optional_params.api_key
|
||||
or litellm.api_key
|
||||
or litellm.azure_key
|
||||
or get_secret("AZURE_OPENAI_API_KEY")
|
||||
or get_secret("AZURE_API_KEY")
|
||||
) # type: ignore
|
||||
|
||||
extra_body = optional_params.get("extra_body", {})
|
||||
azure_ad_token: Optional[str] = None
|
||||
if extra_body is not None:
|
||||
azure_ad_token = extra_body.pop("azure_ad_token", None)
|
||||
else:
|
||||
azure_ad_token = get_secret("AZURE_AD_TOKEN") # type: ignore
|
||||
|
||||
response = azure_assistants_api.get_assistants(
|
||||
api_base=api_base,
|
||||
api_key=api_key,
|
||||
api_version=api_version,
|
||||
azure_ad_token=azure_ad_token,
|
||||
timeout=timeout,
|
||||
max_retries=optional_params.max_retries,
|
||||
client=client,
|
||||
aget_assistants=aget_assistants, # type: ignore
|
||||
)
|
||||
else:
|
||||
raise litellm.exceptions.BadRequestError(
|
||||
|
|
@ -127,7 +181,9 @@ def get_assistants(
|
|||
### THREADS ###
|
||||
|
||||
|
||||
async def acreate_thread(custom_llm_provider: Literal["openai"], **kwargs) -> Thread:
|
||||
async def acreate_thread(
|
||||
custom_llm_provider: Literal["openai", "azure"], **kwargs
|
||||
) -> Thread:
|
||||
loop = asyncio.get_event_loop()
|
||||
### PASS ARGS TO GET ASSISTANTS ###
|
||||
kwargs["acreate_thread"] = True
|
||||
|
|
@ -161,7 +217,7 @@ async def acreate_thread(custom_llm_provider: Literal["openai"], **kwargs) -> Th
|
|||
|
||||
|
||||
def create_thread(
|
||||
custom_llm_provider: Literal["openai"],
|
||||
custom_llm_provider: Literal["openai", "azure"],
|
||||
messages: Optional[Iterable[OpenAICreateThreadParamsMessage]] = None,
|
||||
metadata: Optional[dict] = None,
|
||||
tool_resources: Optional[OpenAICreateThreadParamsToolResources] = None,
|
||||
|
|
@ -241,6 +297,47 @@ def create_thread(
|
|||
client=client,
|
||||
acreate_thread=acreate_thread,
|
||||
)
|
||||
elif custom_llm_provider == "azure":
|
||||
api_base = (
|
||||
optional_params.api_base or litellm.api_base or get_secret("AZURE_API_BASE")
|
||||
) # type: ignore
|
||||
|
||||
api_version = (
|
||||
optional_params.api_version
|
||||
or litellm.api_version
|
||||
or get_secret("AZURE_API_VERSION")
|
||||
) # type: ignore
|
||||
|
||||
api_key = (
|
||||
optional_params.api_key
|
||||
or litellm.api_key
|
||||
or litellm.azure_key
|
||||
or get_secret("AZURE_OPENAI_API_KEY")
|
||||
or get_secret("AZURE_API_KEY")
|
||||
) # type: ignore
|
||||
|
||||
extra_body = optional_params.get("extra_body", {})
|
||||
azure_ad_token = None
|
||||
if extra_body is not None:
|
||||
azure_ad_token = extra_body.pop("azure_ad_token", None)
|
||||
else:
|
||||
azure_ad_token = get_secret("AZURE_AD_TOKEN") # type: ignore
|
||||
|
||||
if isinstance(client, OpenAI):
|
||||
client = None # only pass client if it's AzureOpenAI
|
||||
|
||||
response = azure_assistants_api.create_thread(
|
||||
messages=messages,
|
||||
metadata=metadata,
|
||||
api_base=api_base,
|
||||
api_key=api_key,
|
||||
azure_ad_token=azure_ad_token,
|
||||
api_version=api_version,
|
||||
timeout=timeout,
|
||||
max_retries=optional_params.max_retries,
|
||||
client=client,
|
||||
acreate_thread=acreate_thread,
|
||||
) # type :ignore
|
||||
else:
|
||||
raise litellm.exceptions.BadRequestError(
|
||||
message="LiteLLM doesn't support {} for 'create_thread'. Only 'openai' is supported.".format(
|
||||
|
|
@ -254,11 +351,11 @@ def create_thread(
|
|||
request=httpx.Request(method="create_thread", url="https://github.com/BerriAI/litellm"), # type: ignore
|
||||
),
|
||||
)
|
||||
return response
|
||||
return response # type: ignore
|
||||
|
||||
|
||||
async def aget_thread(
|
||||
custom_llm_provider: Literal["openai"],
|
||||
custom_llm_provider: Literal["openai", "azure"],
|
||||
thread_id: str,
|
||||
client: Optional[AsyncOpenAI] = None,
|
||||
**kwargs,
|
||||
|
|
@ -296,9 +393,9 @@ async def aget_thread(
|
|||
|
||||
|
||||
def get_thread(
|
||||
custom_llm_provider: Literal["openai"],
|
||||
custom_llm_provider: Literal["openai", "azure"],
|
||||
thread_id: str,
|
||||
client: Optional[OpenAI] = None,
|
||||
client=None,
|
||||
**kwargs,
|
||||
) -> Thread:
|
||||
"""Get the thread object, given a thread_id"""
|
||||
|
|
@ -342,6 +439,7 @@ def get_thread(
|
|||
or litellm.openai_key
|
||||
or os.getenv("OPENAI_API_KEY")
|
||||
)
|
||||
|
||||
response = openai_assistants_api.get_thread(
|
||||
thread_id=thread_id,
|
||||
api_base=api_base,
|
||||
|
|
@ -352,6 +450,46 @@ def get_thread(
|
|||
client=client,
|
||||
aget_thread=aget_thread,
|
||||
)
|
||||
elif custom_llm_provider == "azure":
|
||||
api_base = (
|
||||
optional_params.api_base or litellm.api_base or get_secret("AZURE_API_BASE")
|
||||
) # type: ignore
|
||||
|
||||
api_version = (
|
||||
optional_params.api_version
|
||||
or litellm.api_version
|
||||
or get_secret("AZURE_API_VERSION")
|
||||
) # type: ignore
|
||||
|
||||
api_key = (
|
||||
optional_params.api_key
|
||||
or litellm.api_key
|
||||
or litellm.azure_key
|
||||
or get_secret("AZURE_OPENAI_API_KEY")
|
||||
or get_secret("AZURE_API_KEY")
|
||||
) # type: ignore
|
||||
|
||||
extra_body = optional_params.get("extra_body", {})
|
||||
azure_ad_token = None
|
||||
if extra_body is not None:
|
||||
azure_ad_token = extra_body.pop("azure_ad_token", None)
|
||||
else:
|
||||
azure_ad_token = get_secret("AZURE_AD_TOKEN") # type: ignore
|
||||
|
||||
if isinstance(client, OpenAI):
|
||||
client = None # only pass client if it's AzureOpenAI
|
||||
|
||||
response = azure_assistants_api.get_thread(
|
||||
thread_id=thread_id,
|
||||
api_base=api_base,
|
||||
api_key=api_key,
|
||||
azure_ad_token=azure_ad_token,
|
||||
api_version=api_version,
|
||||
timeout=timeout,
|
||||
max_retries=optional_params.max_retries,
|
||||
client=client,
|
||||
aget_thread=aget_thread,
|
||||
)
|
||||
else:
|
||||
raise litellm.exceptions.BadRequestError(
|
||||
message="LiteLLM doesn't support {} for 'get_thread'. Only 'openai' is supported.".format(
|
||||
|
|
@ -365,20 +503,20 @@ def get_thread(
|
|||
request=httpx.Request(method="create_thread", url="https://github.com/BerriAI/litellm"), # type: ignore
|
||||
),
|
||||
)
|
||||
return response
|
||||
return response # type: ignore
|
||||
|
||||
|
||||
### MESSAGES ###
|
||||
|
||||
|
||||
async def a_add_message(
|
||||
custom_llm_provider: Literal["openai"],
|
||||
custom_llm_provider: Literal["openai", "azure"],
|
||||
thread_id: str,
|
||||
role: Literal["user", "assistant"],
|
||||
content: str,
|
||||
attachments: Optional[List[Attachment]] = None,
|
||||
metadata: Optional[dict] = None,
|
||||
client: Optional[AsyncOpenAI] = None,
|
||||
client=None,
|
||||
**kwargs,
|
||||
) -> OpenAIMessage:
|
||||
loop = asyncio.get_event_loop()
|
||||
|
|
@ -425,22 +563,30 @@ async def a_add_message(
|
|||
|
||||
|
||||
def add_message(
|
||||
custom_llm_provider: Literal["openai"],
|
||||
custom_llm_provider: Literal["openai", "azure"],
|
||||
thread_id: str,
|
||||
role: Literal["user", "assistant"],
|
||||
content: str,
|
||||
attachments: Optional[List[Attachment]] = None,
|
||||
metadata: Optional[dict] = None,
|
||||
client: Optional[OpenAI] = None,
|
||||
client=None,
|
||||
**kwargs,
|
||||
) -> OpenAIMessage:
|
||||
### COMMON OBJECTS ###
|
||||
a_add_message = kwargs.pop("a_add_message", None)
|
||||
message_data = MessageData(
|
||||
_message_data = MessageData(
|
||||
role=role, content=content, attachments=attachments, metadata=metadata
|
||||
)
|
||||
optional_params = GenericLiteLLMParams(**kwargs)
|
||||
|
||||
message_data = get_optional_params_add_message(
|
||||
role=_message_data["role"],
|
||||
content=_message_data["content"],
|
||||
attachments=_message_data["attachments"],
|
||||
metadata=_message_data["metadata"],
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
)
|
||||
|
||||
### TIMEOUT LOGIC ###
|
||||
timeout = optional_params.timeout or kwargs.get("request_timeout", 600) or 600
|
||||
# set timeout for 10 minutes by default
|
||||
|
|
@ -489,6 +635,44 @@ def add_message(
|
|||
client=client,
|
||||
a_add_message=a_add_message,
|
||||
)
|
||||
elif custom_llm_provider == "azure":
|
||||
api_base = (
|
||||
optional_params.api_base or litellm.api_base or get_secret("AZURE_API_BASE")
|
||||
) # type: ignore
|
||||
|
||||
api_version = (
|
||||
optional_params.api_version
|
||||
or litellm.api_version
|
||||
or get_secret("AZURE_API_VERSION")
|
||||
) # type: ignore
|
||||
|
||||
api_key = (
|
||||
optional_params.api_key
|
||||
or litellm.api_key
|
||||
or litellm.azure_key
|
||||
or get_secret("AZURE_OPENAI_API_KEY")
|
||||
or get_secret("AZURE_API_KEY")
|
||||
) # type: ignore
|
||||
|
||||
extra_body = optional_params.get("extra_body", {})
|
||||
azure_ad_token = None
|
||||
if extra_body is not None:
|
||||
azure_ad_token = extra_body.pop("azure_ad_token", None)
|
||||
else:
|
||||
azure_ad_token = get_secret("AZURE_AD_TOKEN") # type: ignore
|
||||
|
||||
response = azure_assistants_api.add_message(
|
||||
thread_id=thread_id,
|
||||
message_data=message_data,
|
||||
api_base=api_base,
|
||||
api_key=api_key,
|
||||
api_version=api_version,
|
||||
azure_ad_token=azure_ad_token,
|
||||
timeout=timeout,
|
||||
max_retries=optional_params.max_retries,
|
||||
client=client,
|
||||
a_add_message=a_add_message,
|
||||
)
|
||||
else:
|
||||
raise litellm.exceptions.BadRequestError(
|
||||
message="LiteLLM doesn't support {} for 'create_thread'. Only 'openai' is supported.".format(
|
||||
|
|
@ -503,11 +687,11 @@ def add_message(
|
|||
),
|
||||
)
|
||||
|
||||
return response
|
||||
return response # type: ignore
|
||||
|
||||
|
||||
async def aget_messages(
|
||||
custom_llm_provider: Literal["openai"],
|
||||
custom_llm_provider: Literal["openai", "azure"],
|
||||
thread_id: str,
|
||||
client: Optional[AsyncOpenAI] = None,
|
||||
**kwargs,
|
||||
|
|
@ -552,9 +736,9 @@ async def aget_messages(
|
|||
|
||||
|
||||
def get_messages(
|
||||
custom_llm_provider: Literal["openai"],
|
||||
custom_llm_provider: Literal["openai", "azure"],
|
||||
thread_id: str,
|
||||
client: Optional[OpenAI] = None,
|
||||
client: Optional[Any] = None,
|
||||
**kwargs,
|
||||
) -> SyncCursorPage[OpenAIMessage]:
|
||||
aget_messages = kwargs.pop("aget_messages", None)
|
||||
|
|
@ -607,6 +791,43 @@ def get_messages(
|
|||
client=client,
|
||||
aget_messages=aget_messages,
|
||||
)
|
||||
elif custom_llm_provider == "azure":
|
||||
api_base = (
|
||||
optional_params.api_base or litellm.api_base or get_secret("AZURE_API_BASE")
|
||||
) # type: ignore
|
||||
|
||||
api_version = (
|
||||
optional_params.api_version
|
||||
or litellm.api_version
|
||||
or get_secret("AZURE_API_VERSION")
|
||||
) # type: ignore
|
||||
|
||||
api_key = (
|
||||
optional_params.api_key
|
||||
or litellm.api_key
|
||||
or litellm.azure_key
|
||||
or get_secret("AZURE_OPENAI_API_KEY")
|
||||
or get_secret("AZURE_API_KEY")
|
||||
) # type: ignore
|
||||
|
||||
extra_body = optional_params.get("extra_body", {})
|
||||
azure_ad_token = None
|
||||
if extra_body is not None:
|
||||
azure_ad_token = extra_body.pop("azure_ad_token", None)
|
||||
else:
|
||||
azure_ad_token = get_secret("AZURE_AD_TOKEN") # type: ignore
|
||||
|
||||
response = azure_assistants_api.get_messages(
|
||||
thread_id=thread_id,
|
||||
api_base=api_base,
|
||||
api_key=api_key,
|
||||
api_version=api_version,
|
||||
azure_ad_token=azure_ad_token,
|
||||
timeout=timeout,
|
||||
max_retries=optional_params.max_retries,
|
||||
client=client,
|
||||
aget_messages=aget_messages,
|
||||
)
|
||||
else:
|
||||
raise litellm.exceptions.BadRequestError(
|
||||
message="LiteLLM doesn't support {} for 'get_messages'. Only 'openai' is supported.".format(
|
||||
|
|
@ -621,12 +842,21 @@ def get_messages(
|
|||
),
|
||||
)
|
||||
|
||||
return response
|
||||
return response # type: ignore
|
||||
|
||||
|
||||
### RUNS ###
|
||||
def arun_thread_stream(
|
||||
*,
|
||||
event_handler: Optional[AssistantEventHandler] = None,
|
||||
**kwargs,
|
||||
) -> AsyncAssistantStreamManager[AsyncAssistantEventHandler]:
|
||||
kwargs["arun_thread"] = True
|
||||
return run_thread(stream=True, event_handler=event_handler, **kwargs) # type: ignore
|
||||
|
||||
|
||||
async def arun_thread(
|
||||
custom_llm_provider: Literal["openai"],
|
||||
custom_llm_provider: Literal["openai", "azure"],
|
||||
thread_id: str,
|
||||
assistant_id: str,
|
||||
additional_instructions: Optional[str] = None,
|
||||
|
|
@ -635,7 +865,7 @@ async def arun_thread(
|
|||
model: Optional[str] = None,
|
||||
stream: Optional[bool] = None,
|
||||
tools: Optional[Iterable[AssistantToolParam]] = None,
|
||||
client: Optional[AsyncOpenAI] = None,
|
||||
client: Optional[Any] = None,
|
||||
**kwargs,
|
||||
) -> Run:
|
||||
loop = asyncio.get_event_loop()
|
||||
|
|
@ -684,8 +914,16 @@ async def arun_thread(
|
|||
)
|
||||
|
||||
|
||||
def run_thread_stream(
|
||||
*,
|
||||
event_handler: Optional[AssistantEventHandler] = None,
|
||||
**kwargs,
|
||||
) -> AssistantStreamManager[AssistantEventHandler]:
|
||||
return run_thread(stream=True, event_handler=event_handler, **kwargs) # type: ignore
|
||||
|
||||
|
||||
def run_thread(
|
||||
custom_llm_provider: Literal["openai"],
|
||||
custom_llm_provider: Literal["openai", "azure"],
|
||||
thread_id: str,
|
||||
assistant_id: str,
|
||||
additional_instructions: Optional[str] = None,
|
||||
|
|
@ -694,7 +932,8 @@ def run_thread(
|
|||
model: Optional[str] = None,
|
||||
stream: Optional[bool] = None,
|
||||
tools: Optional[Iterable[AssistantToolParam]] = None,
|
||||
client: Optional[OpenAI] = None,
|
||||
client: Optional[Any] = None,
|
||||
event_handler: Optional[AssistantEventHandler] = None, # for stream=True calls
|
||||
**kwargs,
|
||||
) -> Run:
|
||||
"""Run a given thread + assistant."""
|
||||
|
|
@ -738,6 +977,7 @@ def run_thread(
|
|||
or litellm.openai_key
|
||||
or os.getenv("OPENAI_API_KEY")
|
||||
)
|
||||
|
||||
response = openai_assistants_api.run_thread(
|
||||
thread_id=thread_id,
|
||||
assistant_id=assistant_id,
|
||||
|
|
@ -754,7 +994,52 @@ def run_thread(
|
|||
organization=organization,
|
||||
client=client,
|
||||
arun_thread=arun_thread,
|
||||
event_handler=event_handler,
|
||||
)
|
||||
elif custom_llm_provider == "azure":
|
||||
api_base = (
|
||||
optional_params.api_base or litellm.api_base or get_secret("AZURE_API_BASE")
|
||||
) # type: ignore
|
||||
|
||||
api_version = (
|
||||
optional_params.api_version
|
||||
or litellm.api_version
|
||||
or get_secret("AZURE_API_VERSION")
|
||||
) # type: ignore
|
||||
|
||||
api_key = (
|
||||
optional_params.api_key
|
||||
or litellm.api_key
|
||||
or litellm.azure_key
|
||||
or get_secret("AZURE_OPENAI_API_KEY")
|
||||
or get_secret("AZURE_API_KEY")
|
||||
) # type: ignore
|
||||
|
||||
extra_body = optional_params.get("extra_body", {})
|
||||
azure_ad_token = None
|
||||
if extra_body is not None:
|
||||
azure_ad_token = extra_body.pop("azure_ad_token", None)
|
||||
else:
|
||||
azure_ad_token = get_secret("AZURE_AD_TOKEN") # type: ignore
|
||||
|
||||
response = azure_assistants_api.run_thread(
|
||||
thread_id=thread_id,
|
||||
assistant_id=assistant_id,
|
||||
additional_instructions=additional_instructions,
|
||||
instructions=instructions,
|
||||
metadata=metadata,
|
||||
model=model,
|
||||
stream=stream,
|
||||
tools=tools,
|
||||
api_base=str(api_base) if api_base is not None else None,
|
||||
api_key=str(api_key) if api_key is not None else None,
|
||||
api_version=str(api_version) if api_version is not None else None,
|
||||
azure_ad_token=str(azure_ad_token) if azure_ad_token is not None else None,
|
||||
timeout=timeout,
|
||||
max_retries=optional_params.max_retries,
|
||||
client=client,
|
||||
arun_thread=arun_thread,
|
||||
) # type: ignore
|
||||
else:
|
||||
raise litellm.exceptions.BadRequestError(
|
||||
message="LiteLLM doesn't support {} for 'run_thread'. Only 'openai' is supported.".format(
|
||||
|
|
@ -768,4 +1053,4 @@ def run_thread(
|
|||
request=httpx.Request(method="create_thread", url="https://github.com/BerriAI/litellm"), # type: ignore
|
||||
),
|
||||
)
|
||||
return response
|
||||
return response # type: ignore
|
||||
|
|
|
|||
158
litellm/assistants/utils.py
Normal file
|
|
@ -0,0 +1,158 @@
|
|||
import litellm
|
||||
from typing import Optional, Union
|
||||
from ..types.llms.openai import *
|
||||
|
||||
|
||||
def get_optional_params_add_message(
|
||||
role: Optional[str],
|
||||
content: Optional[
|
||||
Union[
|
||||
str,
|
||||
List[
|
||||
Union[
|
||||
MessageContentTextObject,
|
||||
MessageContentImageFileObject,
|
||||
MessageContentImageURLObject,
|
||||
]
|
||||
],
|
||||
]
|
||||
],
|
||||
attachments: Optional[List[Attachment]],
|
||||
metadata: Optional[dict],
|
||||
custom_llm_provider: str,
|
||||
**kwargs,
|
||||
):
|
||||
"""
|
||||
Azure doesn't support 'attachments' for creating a message
|
||||
|
||||
Reference - https://learn.microsoft.com/en-us/azure/ai-services/openai/assistants-reference-messages?tabs=python#create-message
|
||||
"""
|
||||
passed_params = locals()
|
||||
custom_llm_provider = passed_params.pop("custom_llm_provider")
|
||||
special_params = passed_params.pop("kwargs")
|
||||
for k, v in special_params.items():
|
||||
passed_params[k] = v
|
||||
|
||||
default_params = {
|
||||
"role": None,
|
||||
"content": None,
|
||||
"attachments": None,
|
||||
"metadata": None,
|
||||
}
|
||||
|
||||
non_default_params = {
|
||||
k: v
|
||||
for k, v in passed_params.items()
|
||||
if (k in default_params and v != default_params[k])
|
||||
}
|
||||
optional_params = {}
|
||||
|
||||
## raise exception if non-default value passed for non-openai/azure embedding calls
|
||||
def _check_valid_arg(supported_params):
|
||||
if len(non_default_params.keys()) > 0:
|
||||
keys = list(non_default_params.keys())
|
||||
for k in keys:
|
||||
if (
|
||||
litellm.drop_params is True and k not in supported_params
|
||||
): # drop the unsupported non-default values
|
||||
non_default_params.pop(k, None)
|
||||
elif k not in supported_params:
|
||||
raise litellm.utils.UnsupportedParamsError(
|
||||
status_code=500,
|
||||
message="k={}, not supported by {}. Supported params={}. To drop it from the call, set `litellm.drop_params = True`.".format(
|
||||
k, custom_llm_provider, supported_params
|
||||
),
|
||||
)
|
||||
return non_default_params
|
||||
|
||||
if custom_llm_provider == "openai":
|
||||
optional_params = non_default_params
|
||||
elif custom_llm_provider == "azure":
|
||||
supported_params = (
|
||||
litellm.AzureOpenAIAssistantsAPIConfig().get_supported_openai_create_message_params()
|
||||
)
|
||||
_check_valid_arg(supported_params=supported_params)
|
||||
optional_params = litellm.AzureOpenAIAssistantsAPIConfig().map_openai_params_create_message_params(
|
||||
non_default_params=non_default_params, optional_params=optional_params
|
||||
)
|
||||
for k in passed_params.keys():
|
||||
if k not in default_params.keys():
|
||||
optional_params[k] = passed_params[k]
|
||||
return optional_params
|
||||
|
||||
|
||||
def get_optional_params_image_gen(
|
||||
n: Optional[int] = None,
|
||||
quality: Optional[str] = None,
|
||||
response_format: Optional[str] = None,
|
||||
size: Optional[str] = None,
|
||||
style: Optional[str] = None,
|
||||
user: Optional[str] = None,
|
||||
custom_llm_provider: Optional[str] = None,
|
||||
**kwargs,
|
||||
):
|
||||
# retrieve all parameters passed to the function
|
||||
passed_params = locals()
|
||||
custom_llm_provider = passed_params.pop("custom_llm_provider")
|
||||
special_params = passed_params.pop("kwargs")
|
||||
for k, v in special_params.items():
|
||||
passed_params[k] = v
|
||||
|
||||
default_params = {
|
||||
"n": None,
|
||||
"quality": None,
|
||||
"response_format": None,
|
||||
"size": None,
|
||||
"style": None,
|
||||
"user": None,
|
||||
}
|
||||
|
||||
non_default_params = {
|
||||
k: v
|
||||
for k, v in passed_params.items()
|
||||
if (k in default_params and v != default_params[k])
|
||||
}
|
||||
optional_params = {}
|
||||
|
||||
## raise exception if non-default value passed for non-openai/azure embedding calls
|
||||
def _check_valid_arg(supported_params):
|
||||
if len(non_default_params.keys()) > 0:
|
||||
keys = list(non_default_params.keys())
|
||||
for k in keys:
|
||||
if (
|
||||
litellm.drop_params is True and k not in supported_params
|
||||
): # drop the unsupported non-default values
|
||||
non_default_params.pop(k, None)
|
||||
elif k not in supported_params:
|
||||
raise UnsupportedParamsError(
|
||||
status_code=500,
|
||||
message=f"Setting user/encoding format is not supported by {custom_llm_provider}. To drop it from the call, set `litellm.drop_params = True`.",
|
||||
)
|
||||
return non_default_params
|
||||
|
||||
if (
|
||||
custom_llm_provider == "openai"
|
||||
or custom_llm_provider == "azure"
|
||||
or custom_llm_provider in litellm.openai_compatible_providers
|
||||
):
|
||||
optional_params = non_default_params
|
||||
elif custom_llm_provider == "bedrock":
|
||||
supported_params = ["size"]
|
||||
_check_valid_arg(supported_params=supported_params)
|
||||
if size is not None:
|
||||
width, height = size.split("x")
|
||||
optional_params["width"] = int(width)
|
||||
optional_params["height"] = int(height)
|
||||
elif custom_llm_provider == "vertex_ai":
|
||||
supported_params = ["n"]
|
||||
"""
|
||||
All params here: https://console.cloud.google.com/vertex-ai/publishers/google/model-garden/imagegeneration?project=adroit-crow-413218
|
||||
"""
|
||||
_check_valid_arg(supported_params=supported_params)
|
||||
if n is not None:
|
||||
optional_params["sampleCount"] = int(n)
|
||||
|
||||
for k in passed_params.keys():
|
||||
if k not in default_params.keys():
|
||||
optional_params[k] = passed_params[k]
|
||||
return optional_params
|
||||
|
|
@ -26,6 +26,16 @@ def print_verbose(print_statement):
|
|||
pass
|
||||
|
||||
|
||||
def _get_parent_otel_span_from_kwargs(kwargs: Optional[dict] = None):
|
||||
try:
|
||||
if kwargs is None:
|
||||
return None
|
||||
_metadata = kwargs.get("metadata") or {}
|
||||
return _metadata.get("litellm_parent_otel_span")
|
||||
except:
|
||||
return None
|
||||
|
||||
|
||||
class BaseCache:
|
||||
def set_cache(self, key, value, **kwargs):
|
||||
raise NotImplementedError
|
||||
|
|
@ -233,6 +243,9 @@ class RedisCache(BaseCache):
|
|||
service=ServiceTypes.REDIS,
|
||||
duration=_duration,
|
||||
call_type="increment_cache",
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
parent_otel_span=_get_parent_otel_span_from_kwargs(kwargs),
|
||||
)
|
||||
)
|
||||
return result
|
||||
|
|
@ -246,6 +259,9 @@ class RedisCache(BaseCache):
|
|||
duration=_duration,
|
||||
error=e,
|
||||
call_type="increment_cache",
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
parent_otel_span=_get_parent_otel_span_from_kwargs(kwargs),
|
||||
)
|
||||
)
|
||||
verbose_logger.error(
|
||||
|
|
@ -253,7 +269,6 @@ class RedisCache(BaseCache):
|
|||
str(e),
|
||||
value,
|
||||
)
|
||||
traceback.print_exc()
|
||||
raise e
|
||||
|
||||
async def async_scan_iter(self, pattern: str, count: int = 100) -> list:
|
||||
|
|
@ -277,6 +292,8 @@ class RedisCache(BaseCache):
|
|||
service=ServiceTypes.REDIS,
|
||||
duration=_duration,
|
||||
call_type="async_scan_iter",
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
)
|
||||
) # DO NOT SLOW DOWN CALL B/C OF THIS
|
||||
return keys
|
||||
|
|
@ -291,6 +308,8 @@ class RedisCache(BaseCache):
|
|||
duration=_duration,
|
||||
error=e,
|
||||
call_type="async_scan_iter",
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
)
|
||||
)
|
||||
raise e
|
||||
|
|
@ -304,7 +323,12 @@ class RedisCache(BaseCache):
|
|||
_duration = end_time - start_time
|
||||
asyncio.create_task(
|
||||
self.service_logger_obj.async_service_failure_hook(
|
||||
service=ServiceTypes.REDIS, duration=_duration, error=e
|
||||
service=ServiceTypes.REDIS,
|
||||
duration=_duration,
|
||||
error=e,
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
parent_otel_span=_get_parent_otel_span_from_kwargs(kwargs),
|
||||
)
|
||||
)
|
||||
# NON blocking - notify users Redis is throwing an exception
|
||||
|
|
@ -313,7 +337,6 @@ class RedisCache(BaseCache):
|
|||
str(e),
|
||||
value,
|
||||
)
|
||||
traceback.print_exc()
|
||||
|
||||
key = self.check_and_fix_namespace(key=key)
|
||||
async with _redis_client as redis_client:
|
||||
|
|
@ -333,6 +356,9 @@ class RedisCache(BaseCache):
|
|||
service=ServiceTypes.REDIS,
|
||||
duration=_duration,
|
||||
call_type="async_set_cache",
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
parent_otel_span=_get_parent_otel_span_from_kwargs(kwargs),
|
||||
)
|
||||
)
|
||||
except Exception as e:
|
||||
|
|
@ -344,6 +370,9 @@ class RedisCache(BaseCache):
|
|||
duration=_duration,
|
||||
error=e,
|
||||
call_type="async_set_cache",
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
parent_otel_span=_get_parent_otel_span_from_kwargs(kwargs),
|
||||
)
|
||||
)
|
||||
# NON blocking - notify users Redis is throwing an exception
|
||||
|
|
@ -352,9 +381,8 @@ class RedisCache(BaseCache):
|
|||
str(e),
|
||||
value,
|
||||
)
|
||||
traceback.print_exc()
|
||||
|
||||
async def async_set_cache_pipeline(self, cache_list, ttl=None):
|
||||
async def async_set_cache_pipeline(self, cache_list, ttl=None, **kwargs):
|
||||
"""
|
||||
Use Redis Pipelines for bulk write operations
|
||||
"""
|
||||
|
|
@ -392,6 +420,9 @@ class RedisCache(BaseCache):
|
|||
service=ServiceTypes.REDIS,
|
||||
duration=_duration,
|
||||
call_type="async_set_cache_pipeline",
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
parent_otel_span=_get_parent_otel_span_from_kwargs(kwargs),
|
||||
)
|
||||
)
|
||||
return results
|
||||
|
|
@ -405,6 +436,9 @@ class RedisCache(BaseCache):
|
|||
duration=_duration,
|
||||
error=e,
|
||||
call_type="async_set_cache_pipeline",
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
parent_otel_span=_get_parent_otel_span_from_kwargs(kwargs),
|
||||
)
|
||||
)
|
||||
|
||||
|
|
@ -413,7 +447,6 @@ class RedisCache(BaseCache):
|
|||
str(e),
|
||||
cache_value,
|
||||
)
|
||||
traceback.print_exc()
|
||||
|
||||
async def batch_cache_write(self, key, value, **kwargs):
|
||||
print_verbose(
|
||||
|
|
@ -438,6 +471,9 @@ class RedisCache(BaseCache):
|
|||
service=ServiceTypes.REDIS,
|
||||
duration=_duration,
|
||||
call_type="async_increment",
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
parent_otel_span=_get_parent_otel_span_from_kwargs(kwargs),
|
||||
)
|
||||
)
|
||||
return result
|
||||
|
|
@ -451,6 +487,9 @@ class RedisCache(BaseCache):
|
|||
duration=_duration,
|
||||
error=e,
|
||||
call_type="async_increment",
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
parent_otel_span=_get_parent_otel_span_from_kwargs(kwargs),
|
||||
)
|
||||
)
|
||||
verbose_logger.error(
|
||||
|
|
@ -458,7 +497,6 @@ class RedisCache(BaseCache):
|
|||
str(e),
|
||||
value,
|
||||
)
|
||||
traceback.print_exc()
|
||||
raise e
|
||||
|
||||
async def flush_cache_buffer(self):
|
||||
|
|
@ -495,8 +533,9 @@ class RedisCache(BaseCache):
|
|||
return self._get_cache_logic(cached_response=cached_response)
|
||||
except Exception as e:
|
||||
# NON blocking - notify users Redis is throwing an exception
|
||||
traceback.print_exc()
|
||||
logging.debug("LiteLLM Caching: get() - Got exception from REDIS: ", e)
|
||||
verbose_logger.error(
|
||||
"LiteLLM Caching: get() - Got exception from REDIS: ", e
|
||||
)
|
||||
|
||||
def batch_get_cache(self, key_list) -> dict:
|
||||
"""
|
||||
|
|
@ -544,6 +583,9 @@ class RedisCache(BaseCache):
|
|||
service=ServiceTypes.REDIS,
|
||||
duration=_duration,
|
||||
call_type="async_get_cache",
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
parent_otel_span=_get_parent_otel_span_from_kwargs(kwargs),
|
||||
)
|
||||
)
|
||||
return response
|
||||
|
|
@ -557,6 +599,9 @@ class RedisCache(BaseCache):
|
|||
duration=_duration,
|
||||
error=e,
|
||||
call_type="async_get_cache",
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
parent_otel_span=_get_parent_otel_span_from_kwargs(kwargs),
|
||||
)
|
||||
)
|
||||
# NON blocking - notify users Redis is throwing an exception
|
||||
|
|
@ -587,6 +632,8 @@ class RedisCache(BaseCache):
|
|||
service=ServiceTypes.REDIS,
|
||||
duration=_duration,
|
||||
call_type="async_batch_get_cache",
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
)
|
||||
)
|
||||
|
||||
|
|
@ -612,6 +659,8 @@ class RedisCache(BaseCache):
|
|||
duration=_duration,
|
||||
error=e,
|
||||
call_type="async_batch_get_cache",
|
||||
start_time=start_time,
|
||||
end_time=end_time,
|
||||
)
|
||||
)
|
||||
print_verbose(f"Error occurred in pipeline read - {str(e)}")
|
||||
|
|
@ -646,10 +695,9 @@ class RedisCache(BaseCache):
|
|||
error=e,
|
||||
call_type="sync_ping",
|
||||
)
|
||||
print_verbose(
|
||||
verbose_logger.error(
|
||||
f"LiteLLM Redis Cache PING: - Got exception from REDIS : {str(e)}"
|
||||
)
|
||||
traceback.print_exc()
|
||||
raise e
|
||||
|
||||
async def ping(self) -> bool:
|
||||
|
|
@ -683,10 +731,9 @@ class RedisCache(BaseCache):
|
|||
call_type="async_ping",
|
||||
)
|
||||
)
|
||||
print_verbose(
|
||||
verbose_logger.error(
|
||||
f"LiteLLM Redis Cache PING: - Got exception from REDIS : {str(e)}"
|
||||
)
|
||||
traceback.print_exc()
|
||||
raise e
|
||||
|
||||
async def delete_cache_keys(self, keys):
|
||||
|
|
@ -1138,22 +1185,23 @@ class S3Cache(BaseCache):
|
|||
cached_response = ast.literal_eval(cached_response)
|
||||
if type(cached_response) is not dict:
|
||||
cached_response = dict(cached_response)
|
||||
print_verbose(
|
||||
verbose_logger.debug(
|
||||
f"Got S3 Cache: key: {key}, cached_response {cached_response}. Type Response {type(cached_response)}"
|
||||
)
|
||||
|
||||
return cached_response
|
||||
except botocore.exceptions.ClientError as e:
|
||||
if e.response["Error"]["Code"] == "NoSuchKey":
|
||||
print_verbose(
|
||||
verbose_logger.error(
|
||||
f"S3 Cache: The specified key '{key}' does not exist in the S3 bucket."
|
||||
)
|
||||
return None
|
||||
|
||||
except Exception as e:
|
||||
# NON blocking - notify users S3 is throwing an exception
|
||||
traceback.print_exc()
|
||||
print_verbose(f"S3 Caching: get_cache() - Got exception from S3: {e}")
|
||||
verbose_logger.error(
|
||||
f"S3 Caching: get_cache() - Got exception from S3: {e}"
|
||||
)
|
||||
|
||||
async def async_get_cache(self, key, **kwargs):
|
||||
return self.get_cache(key=key, **kwargs)
|
||||
|
|
@ -1234,8 +1282,7 @@ class DualCache(BaseCache):
|
|||
|
||||
return result
|
||||
except Exception as e:
|
||||
print_verbose(f"LiteLLM Cache: Excepton async add_cache: {str(e)}")
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(f"LiteLLM Cache: Excepton async add_cache: {str(e)}")
|
||||
raise e
|
||||
|
||||
def get_cache(self, key, local_only: bool = False, **kwargs):
|
||||
|
|
@ -1262,7 +1309,7 @@ class DualCache(BaseCache):
|
|||
print_verbose(f"get cache: cache result: {result}")
|
||||
return result
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(traceback.format_exc())
|
||||
|
||||
def batch_get_cache(self, keys: list, local_only: bool = False, **kwargs):
|
||||
try:
|
||||
|
|
@ -1295,7 +1342,7 @@ class DualCache(BaseCache):
|
|||
print_verbose(f"async batch get cache: cache result: {result}")
|
||||
return result
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(traceback.format_exc())
|
||||
|
||||
async def async_get_cache(self, key, local_only: bool = False, **kwargs):
|
||||
# Try to fetch from in-memory cache first
|
||||
|
|
@ -1328,7 +1375,7 @@ class DualCache(BaseCache):
|
|||
print_verbose(f"get cache: cache result: {result}")
|
||||
return result
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(traceback.format_exc())
|
||||
|
||||
async def async_batch_get_cache(
|
||||
self, keys: list, local_only: bool = False, **kwargs
|
||||
|
|
@ -1368,7 +1415,7 @@ class DualCache(BaseCache):
|
|||
|
||||
return result
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(traceback.format_exc())
|
||||
|
||||
async def async_set_cache(self, key, value, local_only: bool = False, **kwargs):
|
||||
print_verbose(
|
||||
|
|
@ -1381,8 +1428,8 @@ class DualCache(BaseCache):
|
|||
if self.redis_cache is not None and local_only == False:
|
||||
await self.redis_cache.async_set_cache(key, value, **kwargs)
|
||||
except Exception as e:
|
||||
print_verbose(f"LiteLLM Cache: Excepton async add_cache: {str(e)}")
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(f"LiteLLM Cache: Excepton async add_cache: {str(e)}")
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
|
||||
async def async_batch_set_cache(
|
||||
self, cache_list: list, local_only: bool = False, **kwargs
|
||||
|
|
@ -1401,11 +1448,11 @@ class DualCache(BaseCache):
|
|||
|
||||
if self.redis_cache is not None and local_only == False:
|
||||
await self.redis_cache.async_set_cache_pipeline(
|
||||
cache_list=cache_list, ttl=kwargs.get("ttl", None)
|
||||
cache_list=cache_list, ttl=kwargs.get("ttl", None), **kwargs
|
||||
)
|
||||
except Exception as e:
|
||||
print_verbose(f"LiteLLM Cache: Excepton async add_cache: {str(e)}")
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(f"LiteLLM Cache: Excepton async add_cache: {str(e)}")
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
|
||||
async def async_increment_cache(
|
||||
self, key, value: float, local_only: bool = False, **kwargs
|
||||
|
|
@ -1429,8 +1476,8 @@ class DualCache(BaseCache):
|
|||
|
||||
return result
|
||||
except Exception as e:
|
||||
print_verbose(f"LiteLLM Cache: Excepton async add_cache: {str(e)}")
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(f"LiteLLM Cache: Excepton async add_cache: {str(e)}")
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
raise e
|
||||
|
||||
def flush_cache(self):
|
||||
|
|
@ -1846,8 +1893,8 @@ class Cache:
|
|||
)
|
||||
self.cache.set_cache(cache_key, cached_data, **kwargs)
|
||||
except Exception as e:
|
||||
print_verbose(f"LiteLLM Cache: Excepton add_cache: {str(e)}")
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(f"LiteLLM Cache: Excepton add_cache: {str(e)}")
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
pass
|
||||
|
||||
async def async_add_cache(self, result, *args, **kwargs):
|
||||
|
|
@ -1864,8 +1911,8 @@ class Cache:
|
|||
)
|
||||
await self.cache.async_set_cache(cache_key, cached_data, **kwargs)
|
||||
except Exception as e:
|
||||
print_verbose(f"LiteLLM Cache: Excepton add_cache: {str(e)}")
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(f"LiteLLM Cache: Excepton add_cache: {str(e)}")
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
|
||||
async def async_add_cache_pipeline(self, result, *args, **kwargs):
|
||||
"""
|
||||
|
|
@ -1897,8 +1944,8 @@ class Cache:
|
|||
)
|
||||
await asyncio.gather(*tasks)
|
||||
except Exception as e:
|
||||
print_verbose(f"LiteLLM Cache: Excepton add_cache: {str(e)}")
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(f"LiteLLM Cache: Excepton add_cache: {str(e)}")
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
|
||||
async def batch_cache_write(self, result, *args, **kwargs):
|
||||
cache_key, cached_data, kwargs = self._add_cache_logic(
|
||||
|
|
|
|||
352
litellm/cost_calculator.py
Normal file
|
|
@ -0,0 +1,352 @@
|
|||
# What is this?
|
||||
## File for 'response_cost' calculation in Logging
|
||||
from typing import Optional, Union, Literal, List
|
||||
import litellm._logging
|
||||
from litellm.utils import (
|
||||
ModelResponse,
|
||||
EmbeddingResponse,
|
||||
ImageResponse,
|
||||
TranscriptionResponse,
|
||||
TextCompletionResponse,
|
||||
CallTypes,
|
||||
cost_per_token,
|
||||
print_verbose,
|
||||
CostPerToken,
|
||||
token_counter,
|
||||
)
|
||||
import litellm
|
||||
from litellm import verbose_logger
|
||||
|
||||
|
||||
# Extract the number of billion parameters from the model name
|
||||
# only used for together_computer LLMs
|
||||
def get_model_params_and_category(model_name) -> str:
|
||||
"""
|
||||
Helper function for calculating together ai pricing.
|
||||
|
||||
Returns
|
||||
- str - model pricing category if mapped else received model name
|
||||
"""
|
||||
import re
|
||||
|
||||
model_name = model_name.lower()
|
||||
re_params_match = re.search(
|
||||
r"(\d+b)", model_name
|
||||
) # catch all decimals like 3b, 70b, etc
|
||||
category = None
|
||||
if re_params_match is not None:
|
||||
params_match = str(re_params_match.group(1))
|
||||
params_match = params_match.replace("b", "")
|
||||
if params_match is not None:
|
||||
params_billion = float(params_match)
|
||||
else:
|
||||
return model_name
|
||||
# Determine the category based on the number of parameters
|
||||
if params_billion <= 4.0:
|
||||
category = "together-ai-up-to-4b"
|
||||
elif params_billion <= 8.0:
|
||||
category = "together-ai-4.1b-8b"
|
||||
elif params_billion <= 21.0:
|
||||
category = "together-ai-8.1b-21b"
|
||||
elif params_billion <= 41.0:
|
||||
category = "together-ai-21.1b-41b"
|
||||
elif params_billion <= 80.0:
|
||||
category = "together-ai-41.1b-80b"
|
||||
elif params_billion <= 110.0:
|
||||
category = "together-ai-81.1b-110b"
|
||||
if category is not None:
|
||||
return category
|
||||
|
||||
return model_name
|
||||
|
||||
|
||||
def get_replicate_completion_pricing(completion_response=None, total_time=0.0):
|
||||
# see https://replicate.com/pricing
|
||||
# for all litellm currently supported LLMs, almost all requests go to a100_80gb
|
||||
a100_80gb_price_per_second_public = (
|
||||
0.001400 # assume all calls sent to A100 80GB for now
|
||||
)
|
||||
if total_time == 0.0: # total time is in ms
|
||||
start_time = completion_response["created"]
|
||||
end_time = getattr(completion_response, "ended", time.time())
|
||||
total_time = end_time - start_time
|
||||
|
||||
return a100_80gb_price_per_second_public * total_time / 1000
|
||||
|
||||
|
||||
def completion_cost(
|
||||
completion_response=None,
|
||||
model: Optional[str] = None,
|
||||
prompt="",
|
||||
messages: List = [],
|
||||
completion="",
|
||||
total_time=0.0, # used for replicate, sagemaker
|
||||
call_type: Literal[
|
||||
"embedding",
|
||||
"aembedding",
|
||||
"completion",
|
||||
"acompletion",
|
||||
"atext_completion",
|
||||
"text_completion",
|
||||
"image_generation",
|
||||
"aimage_generation",
|
||||
"moderation",
|
||||
"amoderation",
|
||||
"atranscription",
|
||||
"transcription",
|
||||
"aspeech",
|
||||
"speech",
|
||||
] = "completion",
|
||||
### REGION ###
|
||||
custom_llm_provider=None,
|
||||
region_name=None, # used for bedrock pricing
|
||||
### IMAGE GEN ###
|
||||
size=None,
|
||||
quality=None,
|
||||
n=None, # number of images
|
||||
### CUSTOM PRICING ###
|
||||
custom_cost_per_token: Optional[CostPerToken] = None,
|
||||
custom_cost_per_second: Optional[float] = None,
|
||||
) -> float:
|
||||
"""
|
||||
Calculate the cost of a given completion call fot GPT-3.5-turbo, llama2, any litellm supported llm.
|
||||
|
||||
Parameters:
|
||||
completion_response (litellm.ModelResponses): [Required] The response received from a LiteLLM completion request.
|
||||
|
||||
[OPTIONAL PARAMS]
|
||||
model (str): Optional. The name of the language model used in the completion calls
|
||||
prompt (str): Optional. The input prompt passed to the llm
|
||||
completion (str): Optional. The output completion text from the llm
|
||||
total_time (float): Optional. (Only used for Replicate LLMs) The total time used for the request in seconds
|
||||
custom_cost_per_token: Optional[CostPerToken]: the cost per input + output token for the llm api call.
|
||||
custom_cost_per_second: Optional[float]: the cost per second for the llm api call.
|
||||
|
||||
Returns:
|
||||
float: The cost in USD dollars for the completion based on the provided parameters.
|
||||
|
||||
Exceptions:
|
||||
Raises exception if model not in the litellm model cost map. Register model, via custom pricing or PR - https://github.com/BerriAI/litellm/blob/main/model_prices_and_context_window.json
|
||||
|
||||
|
||||
Note:
|
||||
- If completion_response is provided, the function extracts token information and the model name from it.
|
||||
- If completion_response is not provided, the function calculates token counts based on the model and input text.
|
||||
- The cost is calculated based on the model, prompt tokens, and completion tokens.
|
||||
- For certain models containing "togethercomputer" in the name, prices are based on the model size.
|
||||
- For un-mapped Replicate models, the cost is calculated based on the total time used for the request.
|
||||
"""
|
||||
try:
|
||||
if (
|
||||
(call_type == "aimage_generation" or call_type == "image_generation")
|
||||
and model is not None
|
||||
and isinstance(model, str)
|
||||
and len(model) == 0
|
||||
and custom_llm_provider == "azure"
|
||||
):
|
||||
model = "dall-e-2" # for dall-e-2, azure expects an empty model name
|
||||
# Handle Inputs to completion_cost
|
||||
prompt_tokens = 0
|
||||
completion_tokens = 0
|
||||
custom_llm_provider = None
|
||||
if completion_response is not None:
|
||||
# get input/output tokens from completion_response
|
||||
prompt_tokens = completion_response.get("usage", {}).get("prompt_tokens", 0)
|
||||
completion_tokens = completion_response.get("usage", {}).get(
|
||||
"completion_tokens", 0
|
||||
)
|
||||
total_time = completion_response.get("_response_ms", 0)
|
||||
verbose_logger.debug(
|
||||
f"completion_response response ms: {completion_response.get('_response_ms')} "
|
||||
)
|
||||
model = model or completion_response.get(
|
||||
"model", None
|
||||
) # check if user passed an override for model, if it's none check completion_response['model']
|
||||
if hasattr(completion_response, "_hidden_params"):
|
||||
if (
|
||||
completion_response._hidden_params.get("model", None) is not None
|
||||
and len(completion_response._hidden_params["model"]) > 0
|
||||
):
|
||||
model = completion_response._hidden_params.get("model", model)
|
||||
custom_llm_provider = completion_response._hidden_params.get(
|
||||
"custom_llm_provider", ""
|
||||
)
|
||||
region_name = completion_response._hidden_params.get(
|
||||
"region_name", region_name
|
||||
)
|
||||
size = completion_response._hidden_params.get(
|
||||
"optional_params", {}
|
||||
).get(
|
||||
"size", "1024-x-1024"
|
||||
) # openai default
|
||||
quality = completion_response._hidden_params.get(
|
||||
"optional_params", {}
|
||||
).get(
|
||||
"quality", "standard"
|
||||
) # openai default
|
||||
n = completion_response._hidden_params.get("optional_params", {}).get(
|
||||
"n", 1
|
||||
) # openai default
|
||||
else:
|
||||
if len(messages) > 0:
|
||||
prompt_tokens = token_counter(model=model, messages=messages)
|
||||
elif len(prompt) > 0:
|
||||
prompt_tokens = token_counter(model=model, text=prompt)
|
||||
completion_tokens = token_counter(model=model, text=completion)
|
||||
if model is None:
|
||||
raise ValueError(
|
||||
f"Model is None and does not exist in passed completion_response. Passed completion_response={completion_response}, model={model}"
|
||||
)
|
||||
|
||||
if (
|
||||
call_type == CallTypes.image_generation.value
|
||||
or call_type == CallTypes.aimage_generation.value
|
||||
):
|
||||
### IMAGE GENERATION COST CALCULATION ###
|
||||
if custom_llm_provider == "vertex_ai":
|
||||
# https://cloud.google.com/vertex-ai/generative-ai/pricing
|
||||
# Vertex Charges Flat $0.20 per image
|
||||
return 0.020
|
||||
|
||||
# fix size to match naming convention
|
||||
if "x" in size and "-x-" not in size:
|
||||
size = size.replace("x", "-x-")
|
||||
image_gen_model_name = f"{size}/{model}"
|
||||
image_gen_model_name_with_quality = image_gen_model_name
|
||||
if quality is not None:
|
||||
image_gen_model_name_with_quality = f"{quality}/{image_gen_model_name}"
|
||||
size = size.split("-x-")
|
||||
height = int(size[0]) # if it's 1024-x-1024 vs. 1024x1024
|
||||
width = int(size[1])
|
||||
verbose_logger.debug(f"image_gen_model_name: {image_gen_model_name}")
|
||||
verbose_logger.debug(
|
||||
f"image_gen_model_name_with_quality: {image_gen_model_name_with_quality}"
|
||||
)
|
||||
if image_gen_model_name in litellm.model_cost:
|
||||
return (
|
||||
litellm.model_cost[image_gen_model_name]["input_cost_per_pixel"]
|
||||
* height
|
||||
* width
|
||||
* n
|
||||
)
|
||||
elif image_gen_model_name_with_quality in litellm.model_cost:
|
||||
return (
|
||||
litellm.model_cost[image_gen_model_name_with_quality][
|
||||
"input_cost_per_pixel"
|
||||
]
|
||||
* height
|
||||
* width
|
||||
* n
|
||||
)
|
||||
else:
|
||||
raise Exception(
|
||||
f"Model={image_gen_model_name} not found in completion cost model map"
|
||||
)
|
||||
# Calculate cost based on prompt_tokens, completion_tokens
|
||||
if (
|
||||
"togethercomputer" in model
|
||||
or "together_ai" in model
|
||||
or custom_llm_provider == "together_ai"
|
||||
):
|
||||
# together ai prices based on size of llm
|
||||
# get_model_params_and_category takes a model name and returns the category of LLM size it is in model_prices_and_context_window.json
|
||||
model = get_model_params_and_category(model)
|
||||
# replicate llms are calculate based on time for request running
|
||||
# see https://replicate.com/pricing
|
||||
elif (
|
||||
model in litellm.replicate_models or "replicate" in model
|
||||
) and model not in litellm.model_cost:
|
||||
# for unmapped replicate model, default to replicate's time tracking logic
|
||||
return get_replicate_completion_pricing(completion_response, total_time)
|
||||
|
||||
if model is None:
|
||||
raise ValueError(
|
||||
f"Model is None and does not exist in passed completion_response. Passed completion_response={completion_response}, model={model}"
|
||||
)
|
||||
|
||||
(
|
||||
prompt_tokens_cost_usd_dollar,
|
||||
completion_tokens_cost_usd_dollar,
|
||||
) = cost_per_token(
|
||||
model=model,
|
||||
prompt_tokens=prompt_tokens,
|
||||
completion_tokens=completion_tokens,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
response_time_ms=total_time,
|
||||
region_name=region_name,
|
||||
custom_cost_per_second=custom_cost_per_second,
|
||||
custom_cost_per_token=custom_cost_per_token,
|
||||
)
|
||||
_final_cost = prompt_tokens_cost_usd_dollar + completion_tokens_cost_usd_dollar
|
||||
print_verbose(
|
||||
f"final cost: {_final_cost}; prompt_tokens_cost_usd_dollar: {prompt_tokens_cost_usd_dollar}; completion_tokens_cost_usd_dollar: {completion_tokens_cost_usd_dollar}"
|
||||
)
|
||||
return _final_cost
|
||||
except Exception as e:
|
||||
raise e
|
||||
|
||||
|
||||
def response_cost_calculator(
|
||||
response_object: Union[
|
||||
ModelResponse,
|
||||
EmbeddingResponse,
|
||||
ImageResponse,
|
||||
TranscriptionResponse,
|
||||
TextCompletionResponse,
|
||||
],
|
||||
model: str,
|
||||
custom_llm_provider: str,
|
||||
call_type: Literal[
|
||||
"embedding",
|
||||
"aembedding",
|
||||
"completion",
|
||||
"acompletion",
|
||||
"atext_completion",
|
||||
"text_completion",
|
||||
"image_generation",
|
||||
"aimage_generation",
|
||||
"moderation",
|
||||
"amoderation",
|
||||
"atranscription",
|
||||
"transcription",
|
||||
"aspeech",
|
||||
"speech",
|
||||
],
|
||||
optional_params: dict,
|
||||
cache_hit: Optional[bool] = None,
|
||||
base_model: Optional[str] = None,
|
||||
custom_pricing: Optional[bool] = None,
|
||||
) -> Optional[float]:
|
||||
try:
|
||||
response_cost: float = 0.0
|
||||
if cache_hit is not None and cache_hit is True:
|
||||
response_cost = 0.0
|
||||
else:
|
||||
response_object._hidden_params["optional_params"] = optional_params
|
||||
if isinstance(response_object, ImageResponse):
|
||||
response_cost = completion_cost(
|
||||
completion_response=response_object,
|
||||
model=model,
|
||||
call_type=call_type,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
)
|
||||
else:
|
||||
if (
|
||||
model in litellm.model_cost
|
||||
and custom_pricing is not None
|
||||
and custom_llm_provider is True
|
||||
): # override defaults if custom pricing is set
|
||||
base_model = model
|
||||
# base_model defaults to None if not set on model_info
|
||||
response_cost = completion_cost(
|
||||
completion_response=response_object,
|
||||
call_type=call_type,
|
||||
model=base_model,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
)
|
||||
return response_cost
|
||||
except litellm.NotFoundError as e:
|
||||
print_verbose(
|
||||
f"Model={model} for LLM Provider={custom_llm_provider} not found in completion cost map."
|
||||
)
|
||||
return None
|
||||
|
|
@ -20,18 +20,44 @@ class AuthenticationError(openai.AuthenticationError): # type: ignore
|
|||
message,
|
||||
llm_provider,
|
||||
model,
|
||||
response: httpx.Response,
|
||||
response: Optional[httpx.Response] = None,
|
||||
litellm_debug_info: Optional[str] = None,
|
||||
max_retries: Optional[int] = None,
|
||||
num_retries: Optional[int] = None,
|
||||
):
|
||||
self.status_code = 401
|
||||
self.message = message
|
||||
self.llm_provider = llm_provider
|
||||
self.model = model
|
||||
self.litellm_debug_info = litellm_debug_info
|
||||
self.max_retries = max_retries
|
||||
self.num_retries = num_retries
|
||||
self.response = response or httpx.Response(
|
||||
status_code=self.status_code,
|
||||
request=httpx.Request(
|
||||
method="GET", url="https://litellm.ai"
|
||||
), # mock request object
|
||||
)
|
||||
super().__init__(
|
||||
self.message, response=response, body=None
|
||||
self.message, response=self.response, body=None
|
||||
) # Call the base class constructor with the parameters it needs
|
||||
|
||||
def __str__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
def __repr__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
|
||||
# raise when invalid models passed, example gpt-8
|
||||
class NotFoundError(openai.NotFoundError): # type: ignore
|
||||
|
|
@ -40,18 +66,44 @@ class NotFoundError(openai.NotFoundError): # type: ignore
|
|||
message,
|
||||
model,
|
||||
llm_provider,
|
||||
response: httpx.Response,
|
||||
response: Optional[httpx.Response] = None,
|
||||
litellm_debug_info: Optional[str] = None,
|
||||
max_retries: Optional[int] = None,
|
||||
num_retries: Optional[int] = None,
|
||||
):
|
||||
self.status_code = 404
|
||||
self.message = message
|
||||
self.model = model
|
||||
self.llm_provider = llm_provider
|
||||
self.litellm_debug_info = litellm_debug_info
|
||||
self.max_retries = max_retries
|
||||
self.num_retries = num_retries
|
||||
self.response = response or httpx.Response(
|
||||
status_code=self.status_code,
|
||||
request=httpx.Request(
|
||||
method="GET", url="https://litellm.ai"
|
||||
), # mock request object
|
||||
)
|
||||
super().__init__(
|
||||
self.message, response=response, body=None
|
||||
self.message, response=self.response, body=None
|
||||
) # Call the base class constructor with the parameters it needs
|
||||
|
||||
def __str__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
def __repr__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
|
||||
class BadRequestError(openai.BadRequestError): # type: ignore
|
||||
def __init__(
|
||||
|
|
@ -61,6 +113,8 @@ class BadRequestError(openai.BadRequestError): # type: ignore
|
|||
llm_provider,
|
||||
response: Optional[httpx.Response] = None,
|
||||
litellm_debug_info: Optional[str] = None,
|
||||
max_retries: Optional[int] = None,
|
||||
num_retries: Optional[int] = None,
|
||||
):
|
||||
self.status_code = 400
|
||||
self.message = message
|
||||
|
|
@ -73,10 +127,28 @@ class BadRequestError(openai.BadRequestError): # type: ignore
|
|||
method="GET", url="https://litellm.ai"
|
||||
), # mock request object
|
||||
)
|
||||
self.max_retries = max_retries
|
||||
self.num_retries = num_retries
|
||||
super().__init__(
|
||||
self.message, response=response, body=None
|
||||
) # Call the base class constructor with the parameters it needs
|
||||
|
||||
def __str__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
def __repr__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
|
||||
class UnprocessableEntityError(openai.UnprocessableEntityError): # type: ignore
|
||||
def __init__(
|
||||
|
|
@ -86,20 +158,46 @@ class UnprocessableEntityError(openai.UnprocessableEntityError): # type: ignore
|
|||
llm_provider,
|
||||
response: httpx.Response,
|
||||
litellm_debug_info: Optional[str] = None,
|
||||
max_retries: Optional[int] = None,
|
||||
num_retries: Optional[int] = None,
|
||||
):
|
||||
self.status_code = 422
|
||||
self.message = message
|
||||
self.model = model
|
||||
self.llm_provider = llm_provider
|
||||
self.litellm_debug_info = litellm_debug_info
|
||||
self.max_retries = max_retries
|
||||
self.num_retries = num_retries
|
||||
super().__init__(
|
||||
self.message, response=response, body=None
|
||||
) # Call the base class constructor with the parameters it needs
|
||||
|
||||
def __str__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
def __repr__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
|
||||
class Timeout(openai.APITimeoutError): # type: ignore
|
||||
def __init__(
|
||||
self, message, model, llm_provider, litellm_debug_info: Optional[str] = None
|
||||
self,
|
||||
message,
|
||||
model,
|
||||
llm_provider,
|
||||
litellm_debug_info: Optional[str] = None,
|
||||
max_retries: Optional[int] = None,
|
||||
num_retries: Optional[int] = None,
|
||||
):
|
||||
request = httpx.Request(method="POST", url="https://api.openai.com/v1")
|
||||
super().__init__(
|
||||
|
|
@ -110,10 +208,25 @@ class Timeout(openai.APITimeoutError): # type: ignore
|
|||
self.model = model
|
||||
self.llm_provider = llm_provider
|
||||
self.litellm_debug_info = litellm_debug_info
|
||||
self.max_retries = max_retries
|
||||
self.num_retries = num_retries
|
||||
|
||||
# custom function to convert to str
|
||||
def __str__(self):
|
||||
return str(self.message)
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
def __repr__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
|
||||
class PermissionDeniedError(openai.PermissionDeniedError): # type:ignore
|
||||
|
|
@ -124,16 +237,36 @@ class PermissionDeniedError(openai.PermissionDeniedError): # type:ignore
|
|||
model,
|
||||
response: httpx.Response,
|
||||
litellm_debug_info: Optional[str] = None,
|
||||
max_retries: Optional[int] = None,
|
||||
num_retries: Optional[int] = None,
|
||||
):
|
||||
self.status_code = 403
|
||||
self.message = message
|
||||
self.llm_provider = llm_provider
|
||||
self.model = model
|
||||
self.litellm_debug_info = litellm_debug_info
|
||||
self.max_retries = max_retries
|
||||
self.num_retries = num_retries
|
||||
super().__init__(
|
||||
self.message, response=response, body=None
|
||||
) # Call the base class constructor with the parameters it needs
|
||||
|
||||
def __str__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
def __repr__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
|
||||
class RateLimitError(openai.RateLimitError): # type: ignore
|
||||
def __init__(
|
||||
|
|
@ -141,18 +274,48 @@ class RateLimitError(openai.RateLimitError): # type: ignore
|
|||
message,
|
||||
llm_provider,
|
||||
model,
|
||||
response: httpx.Response,
|
||||
response: Optional[httpx.Response] = None,
|
||||
litellm_debug_info: Optional[str] = None,
|
||||
max_retries: Optional[int] = None,
|
||||
num_retries: Optional[int] = None,
|
||||
):
|
||||
self.status_code = 429
|
||||
self.message = message
|
||||
self.llm_provider = llm_provider
|
||||
self.modle = model
|
||||
self.model = model
|
||||
self.litellm_debug_info = litellm_debug_info
|
||||
self.max_retries = max_retries
|
||||
self.num_retries = num_retries
|
||||
if response is None:
|
||||
self.response = httpx.Response(
|
||||
status_code=429,
|
||||
request=httpx.Request(
|
||||
method="POST",
|
||||
url=" https://cloud.google.com/vertex-ai/",
|
||||
),
|
||||
)
|
||||
else:
|
||||
self.response = response
|
||||
super().__init__(
|
||||
self.message, response=response, body=None
|
||||
self.message, response=self.response, body=None
|
||||
) # Call the base class constructor with the parameters it needs
|
||||
|
||||
def __str__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
def __repr__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
|
||||
# sub class of rate limit error - meant to give more granularity for error handling context window exceeded errors
|
||||
class ContextWindowExceededError(BadRequestError): # type: ignore
|
||||
|
|
@ -174,8 +337,25 @@ class ContextWindowExceededError(BadRequestError): # type: ignore
|
|||
model=self.model, # type: ignore
|
||||
llm_provider=self.llm_provider, # type: ignore
|
||||
response=response,
|
||||
litellm_debug_info=self.litellm_debug_info,
|
||||
) # Call the base class constructor with the parameters it needs
|
||||
|
||||
def __str__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
def __repr__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
|
||||
# sub class of bad request error - meant to help us catch guardrails-related errors on proxy.
|
||||
class RejectedRequestError(BadRequestError): # type: ignore
|
||||
|
|
@ -200,8 +380,25 @@ class RejectedRequestError(BadRequestError): # type: ignore
|
|||
model=self.model, # type: ignore
|
||||
llm_provider=self.llm_provider, # type: ignore
|
||||
response=response,
|
||||
litellm_debug_info=self.litellm_debug_info,
|
||||
) # Call the base class constructor with the parameters it needs
|
||||
|
||||
def __str__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
def __repr__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
|
||||
class ContentPolicyViolationError(BadRequestError): # type: ignore
|
||||
# Error code: 400 - {'error': {'code': 'content_policy_violation', 'message': 'Your request was rejected as a result of our safety system. Image descriptions generated from your prompt may contain text that is not allowed by our safety system. If you believe this was done in error, your request may succeed if retried, or by adjusting your prompt.', 'param': None, 'type': 'invalid_request_error'}}
|
||||
|
|
@ -223,8 +420,25 @@ class ContentPolicyViolationError(BadRequestError): # type: ignore
|
|||
model=self.model, # type: ignore
|
||||
llm_provider=self.llm_provider, # type: ignore
|
||||
response=response,
|
||||
litellm_debug_info=self.litellm_debug_info,
|
||||
) # Call the base class constructor with the parameters it needs
|
||||
|
||||
def __str__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
def __repr__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
|
||||
class ServiceUnavailableError(openai.APIStatusError): # type: ignore
|
||||
def __init__(
|
||||
|
|
@ -232,18 +446,97 @@ class ServiceUnavailableError(openai.APIStatusError): # type: ignore
|
|||
message,
|
||||
llm_provider,
|
||||
model,
|
||||
response: httpx.Response,
|
||||
response: Optional[httpx.Response] = None,
|
||||
litellm_debug_info: Optional[str] = None,
|
||||
max_retries: Optional[int] = None,
|
||||
num_retries: Optional[int] = None,
|
||||
):
|
||||
self.status_code = 503
|
||||
self.message = message
|
||||
self.llm_provider = llm_provider
|
||||
self.model = model
|
||||
self.litellm_debug_info = litellm_debug_info
|
||||
self.max_retries = max_retries
|
||||
self.num_retries = num_retries
|
||||
if response is None:
|
||||
self.response = httpx.Response(
|
||||
status_code=self.status_code,
|
||||
request=httpx.Request(
|
||||
method="POST",
|
||||
url=" https://cloud.google.com/vertex-ai/",
|
||||
),
|
||||
)
|
||||
else:
|
||||
self.response = response
|
||||
super().__init__(
|
||||
self.message, response=response, body=None
|
||||
self.message, response=self.response, body=None
|
||||
) # Call the base class constructor with the parameters it needs
|
||||
|
||||
def __str__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
def __repr__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
|
||||
class InternalServerError(openai.InternalServerError): # type: ignore
|
||||
def __init__(
|
||||
self,
|
||||
message,
|
||||
llm_provider,
|
||||
model,
|
||||
response: Optional[httpx.Response] = None,
|
||||
litellm_debug_info: Optional[str] = None,
|
||||
max_retries: Optional[int] = None,
|
||||
num_retries: Optional[int] = None,
|
||||
):
|
||||
self.status_code = 500
|
||||
self.message = message
|
||||
self.llm_provider = llm_provider
|
||||
self.model = model
|
||||
self.litellm_debug_info = litellm_debug_info
|
||||
self.max_retries = max_retries
|
||||
self.num_retries = num_retries
|
||||
if response is None:
|
||||
self.response = httpx.Response(
|
||||
status_code=self.status_code,
|
||||
request=httpx.Request(
|
||||
method="POST",
|
||||
url=" https://cloud.google.com/vertex-ai/",
|
||||
),
|
||||
)
|
||||
else:
|
||||
self.response = response
|
||||
super().__init__(
|
||||
self.message, response=self.response, body=None
|
||||
) # Call the base class constructor with the parameters it needs
|
||||
|
||||
def __str__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
def __repr__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
|
||||
# raise this when the API returns an invalid response object - https://github.com/openai/openai-python/blob/1be14ee34a0f8e42d3f9aa5451aa4cb161f1781f/openai/api_requestor.py#L401
|
||||
class APIError(openai.APIError): # type: ignore
|
||||
|
|
@ -255,14 +548,34 @@ class APIError(openai.APIError): # type: ignore
|
|||
model,
|
||||
request: httpx.Request,
|
||||
litellm_debug_info: Optional[str] = None,
|
||||
max_retries: Optional[int] = None,
|
||||
num_retries: Optional[int] = None,
|
||||
):
|
||||
self.status_code = status_code
|
||||
self.message = message
|
||||
self.llm_provider = llm_provider
|
||||
self.model = model
|
||||
self.litellm_debug_info = litellm_debug_info
|
||||
self.max_retries = max_retries
|
||||
self.num_retries = num_retries
|
||||
super().__init__(self.message, request=request, body=None) # type: ignore
|
||||
|
||||
def __str__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
def __repr__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
|
||||
# raised if an invalid request (not get, delete, put, post) is made
|
||||
class APIConnectionError(openai.APIConnectionError): # type: ignore
|
||||
|
|
@ -273,19 +586,45 @@ class APIConnectionError(openai.APIConnectionError): # type: ignore
|
|||
model,
|
||||
request: httpx.Request,
|
||||
litellm_debug_info: Optional[str] = None,
|
||||
max_retries: Optional[int] = None,
|
||||
num_retries: Optional[int] = None,
|
||||
):
|
||||
self.message = message
|
||||
self.llm_provider = llm_provider
|
||||
self.model = model
|
||||
self.status_code = 500
|
||||
self.litellm_debug_info = litellm_debug_info
|
||||
self.max_retries = max_retries
|
||||
self.num_retries = num_retries
|
||||
super().__init__(message=self.message, request=request)
|
||||
|
||||
def __str__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
def __repr__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
|
||||
# raised if an invalid request (not get, delete, put, post) is made
|
||||
class APIResponseValidationError(openai.APIResponseValidationError): # type: ignore
|
||||
def __init__(
|
||||
self, message, llm_provider, model, litellm_debug_info: Optional[str] = None
|
||||
self,
|
||||
message,
|
||||
llm_provider,
|
||||
model,
|
||||
litellm_debug_info: Optional[str] = None,
|
||||
max_retries: Optional[int] = None,
|
||||
num_retries: Optional[int] = None,
|
||||
):
|
||||
self.message = message
|
||||
self.llm_provider = llm_provider
|
||||
|
|
@ -293,8 +632,26 @@ class APIResponseValidationError(openai.APIResponseValidationError): # type: ig
|
|||
request = httpx.Request(method="POST", url="https://api.openai.com/v1")
|
||||
response = httpx.Response(status_code=500, request=request)
|
||||
self.litellm_debug_info = litellm_debug_info
|
||||
self.max_retries = max_retries
|
||||
self.num_retries = num_retries
|
||||
super().__init__(response=response, body=None, message=message)
|
||||
|
||||
def __str__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
def __repr__(self):
|
||||
_message = self.message
|
||||
if self.num_retries:
|
||||
_message += f" LiteLLM Retried: {self.num_retries} times"
|
||||
if self.max_retries:
|
||||
_message += f", LiteLLM Max Retries: {self.max_retries}"
|
||||
return _message
|
||||
|
||||
|
||||
class OpenAIError(openai.OpenAIError): # type: ignore
|
||||
def __init__(self, original_exception):
|
||||
|
|
@ -309,6 +666,27 @@ class OpenAIError(openai.OpenAIError): # type: ignore
|
|||
self.llm_provider = "openai"
|
||||
|
||||
|
||||
LITELLM_EXCEPTION_TYPES = [
|
||||
AuthenticationError,
|
||||
NotFoundError,
|
||||
BadRequestError,
|
||||
UnprocessableEntityError,
|
||||
Timeout,
|
||||
PermissionDeniedError,
|
||||
RateLimitError,
|
||||
ContextWindowExceededError,
|
||||
RejectedRequestError,
|
||||
ContentPolicyViolationError,
|
||||
InternalServerError,
|
||||
ServiceUnavailableError,
|
||||
APIError,
|
||||
APIConnectionError,
|
||||
APIResponseValidationError,
|
||||
OpenAIError,
|
||||
InternalServerError,
|
||||
]
|
||||
|
||||
|
||||
class BudgetExceededError(Exception):
|
||||
def __init__(self, current_cost, max_budget):
|
||||
self.current_cost = current_cost
|
||||
|
|
|
|||
|
|
@ -169,6 +169,5 @@ class AISpendLogger:
|
|||
|
||||
print_verbose(f"AISpend Logging - final data object: {data}")
|
||||
except:
|
||||
# traceback.print_exc()
|
||||
print_verbose(f"AISpend Logging Error - {traceback.format_exc()}")
|
||||
pass
|
||||
|
|
|
|||
|
|
@ -178,6 +178,5 @@ class BerriSpendLogger:
|
|||
print_verbose(f"BerriSpend Logging - final data object: {data}")
|
||||
response = requests.post(url, headers=headers, json=data)
|
||||
except:
|
||||
# traceback.print_exc()
|
||||
print_verbose(f"BerriSpend Logging Error - {traceback.format_exc()}")
|
||||
pass
|
||||
|
|
|
|||
|
|
@ -297,6 +297,5 @@ class ClickhouseLogger:
|
|||
# make request to endpoint with payload
|
||||
verbose_logger.debug(f"Clickhouse Logger - final response = {response}")
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.debug(f"Clickhouse - {str(e)}\n{traceback.format_exc()}")
|
||||
pass
|
||||
|
|
|
|||
|
|
@ -115,7 +115,6 @@ class CustomLogger: # https://docs.litellm.ai/docs/observability/custom_callbac
|
|||
)
|
||||
print_verbose(f"Custom Logger - model call details: {kwargs}")
|
||||
except:
|
||||
traceback.print_exc()
|
||||
print_verbose(f"Custom Logger Error - {traceback.format_exc()}")
|
||||
|
||||
async def async_log_input_event(
|
||||
|
|
@ -130,7 +129,6 @@ class CustomLogger: # https://docs.litellm.ai/docs/observability/custom_callbac
|
|||
)
|
||||
print_verbose(f"Custom Logger - model call details: {kwargs}")
|
||||
except:
|
||||
traceback.print_exc()
|
||||
print_verbose(f"Custom Logger Error - {traceback.format_exc()}")
|
||||
|
||||
def log_event(
|
||||
|
|
@ -146,7 +144,6 @@ class CustomLogger: # https://docs.litellm.ai/docs/observability/custom_callbac
|
|||
end_time,
|
||||
)
|
||||
except:
|
||||
# traceback.print_exc()
|
||||
print_verbose(f"Custom Logger Error - {traceback.format_exc()}")
|
||||
pass
|
||||
|
||||
|
|
@ -163,6 +160,5 @@ class CustomLogger: # https://docs.litellm.ai/docs/observability/custom_callbac
|
|||
end_time,
|
||||
)
|
||||
except:
|
||||
# traceback.print_exc()
|
||||
print_verbose(f"Custom Logger Error - {traceback.format_exc()}")
|
||||
pass
|
||||
|
|
|
|||
|
|
@ -134,7 +134,6 @@ class DataDogLogger:
|
|||
f"Datadog Layer Logging - final response object: {response_obj}"
|
||||
)
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.debug(
|
||||
f"Datadog Layer Error - {str(e)}\n{traceback.format_exc()}"
|
||||
)
|
||||
|
|
|
|||
|
|
@ -85,6 +85,5 @@ class DyanmoDBLogger:
|
|||
)
|
||||
return response
|
||||
except:
|
||||
traceback.print_exc()
|
||||
print_verbose(f"DynamoDB Layer Error - {traceback.format_exc()}")
|
||||
pass
|
||||
|
|
|
|||
|
|
@ -112,6 +112,5 @@ class HeliconeLogger:
|
|||
)
|
||||
print_verbose(f"Helicone Logging - Error {response.text}")
|
||||
except:
|
||||
# traceback.print_exc()
|
||||
print_verbose(f"Helicone Logging Error - {traceback.format_exc()}")
|
||||
pass
|
||||
|
|
|
|||
|
|
@ -69,6 +69,43 @@ class LangFuseLogger:
|
|||
else:
|
||||
self.upstream_langfuse = None
|
||||
|
||||
@staticmethod
|
||||
def add_metadata_from_header(litellm_params: dict, metadata: dict) -> dict:
|
||||
"""
|
||||
Adds metadata from proxy request headers to Langfuse logging if keys start with "langfuse_"
|
||||
and overwrites litellm_params.metadata if already included.
|
||||
|
||||
For example if you want to append your trace to an existing `trace_id` via header, send
|
||||
`headers: { ..., langfuse_existing_trace_id: your-existing-trace-id }` via proxy request.
|
||||
"""
|
||||
if litellm_params is None:
|
||||
return metadata
|
||||
|
||||
if litellm_params.get("proxy_server_request") is None:
|
||||
return metadata
|
||||
|
||||
if metadata is None:
|
||||
metadata = {}
|
||||
|
||||
proxy_headers = (
|
||||
litellm_params.get("proxy_server_request", {}).get("headers", {}) or {}
|
||||
)
|
||||
|
||||
for metadata_param_key in proxy_headers:
|
||||
if metadata_param_key.startswith("langfuse_"):
|
||||
trace_param_key = metadata_param_key.replace("langfuse_", "", 1)
|
||||
if trace_param_key in metadata:
|
||||
verbose_logger.warning(
|
||||
f"Overwriting Langfuse `{trace_param_key}` from request header"
|
||||
)
|
||||
else:
|
||||
verbose_logger.debug(
|
||||
f"Found Langfuse `{trace_param_key}` in request header"
|
||||
)
|
||||
metadata[trace_param_key] = proxy_headers.get(metadata_param_key)
|
||||
|
||||
return metadata
|
||||
|
||||
# def log_error(kwargs, response_obj, start_time, end_time):
|
||||
# generation = trace.generation(
|
||||
# level ="ERROR" # can be any of DEBUG, DEFAULT, WARNING or ERROR
|
||||
|
|
@ -97,6 +134,7 @@ class LangFuseLogger:
|
|||
metadata = (
|
||||
litellm_params.get("metadata", {}) or {}
|
||||
) # if litellm_params['metadata'] == None
|
||||
metadata = self.add_metadata_from_header(litellm_params, metadata)
|
||||
optional_params = copy.deepcopy(kwargs.get("optional_params", {}))
|
||||
|
||||
prompt = {"messages": kwargs.get("messages")}
|
||||
|
|
@ -182,9 +220,11 @@ class LangFuseLogger:
|
|||
verbose_logger.info(f"Langfuse Layer Logging - logging success")
|
||||
|
||||
return {"trace_id": trace_id, "generation_id": generation_id}
|
||||
except:
|
||||
traceback.print_exc()
|
||||
verbose_logger.debug(f"Langfuse Layer Error - {traceback.format_exc()}")
|
||||
except Exception as e:
|
||||
verbose_logger.error(
|
||||
"Langfuse Layer Error(): Exception occured - {}".format(str(e))
|
||||
)
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
return {"trace_id": None, "generation_id": None}
|
||||
|
||||
async def _async_log_event(
|
||||
|
|
@ -396,6 +436,8 @@ class LangFuseLogger:
|
|||
cost = kwargs.get("response_cost", None)
|
||||
print_verbose(f"trace: {cost}")
|
||||
|
||||
clean_metadata["litellm_response_cost"] = cost
|
||||
|
||||
if (
|
||||
litellm._langfuse_default_tags is not None
|
||||
and isinstance(litellm._langfuse_default_tags, list)
|
||||
|
|
|
|||
|
|
@ -44,7 +44,9 @@ class LangsmithLogger:
|
|||
print_verbose(
|
||||
f"Langsmith Logging - project_name: {project_name}, run_name {run_name}"
|
||||
)
|
||||
langsmith_base_url = os.getenv("LANGSMITH_BASE_URL", "https://api.smith.langchain.com")
|
||||
langsmith_base_url = os.getenv(
|
||||
"LANGSMITH_BASE_URL", "https://api.smith.langchain.com"
|
||||
)
|
||||
|
||||
try:
|
||||
print_verbose(
|
||||
|
|
@ -89,9 +91,7 @@ class LangsmithLogger:
|
|||
}
|
||||
|
||||
url = f"{langsmith_base_url}/runs"
|
||||
print_verbose(
|
||||
f"Langsmith Logging - About to send data to {url} ..."
|
||||
)
|
||||
print_verbose(f"Langsmith Logging - About to send data to {url} ...")
|
||||
response = requests.post(
|
||||
url=url,
|
||||
json=data,
|
||||
|
|
@ -106,6 +106,5 @@ class LangsmithLogger:
|
|||
f"Langsmith Layer Logging - final response object: {response_obj}"
|
||||
)
|
||||
except:
|
||||
# traceback.print_exc()
|
||||
print_verbose(f"Langsmith Layer Error - {traceback.format_exc()}")
|
||||
pass
|
||||
|
|
|
|||
|
|
@ -171,7 +171,6 @@ class LogfireLogger:
|
|||
f"Logfire Layer Logging - final response object: {response_obj}"
|
||||
)
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.debug(
|
||||
f"Logfire Layer Error - {str(e)}\n{traceback.format_exc()}"
|
||||
)
|
||||
|
|
|
|||
|
|
@ -14,6 +14,7 @@ def parse_usage(usage):
|
|||
"prompt": usage["prompt_tokens"] if "prompt_tokens" in usage else 0,
|
||||
}
|
||||
|
||||
|
||||
def parse_tool_calls(tool_calls):
|
||||
if tool_calls is None:
|
||||
return None
|
||||
|
|
@ -26,13 +27,13 @@ def parse_tool_calls(tool_calls):
|
|||
"function": {
|
||||
"name": tool_call.function.name,
|
||||
"arguments": tool_call.function.arguments,
|
||||
}
|
||||
},
|
||||
}
|
||||
|
||||
return serialized
|
||||
|
||||
|
||||
return [clean_tool_call(tool_call) for tool_call in tool_calls]
|
||||
|
||||
|
||||
|
||||
def parse_messages(input):
|
||||
|
||||
|
|
@ -176,6 +177,5 @@ class LunaryLogger:
|
|||
)
|
||||
|
||||
except:
|
||||
# traceback.print_exc()
|
||||
print_verbose(f"Lunary Logging Error - {traceback.format_exc()}")
|
||||
pass
|
||||
|
|
|
|||
547
litellm/integrations/opentelemetry.py
Normal file
|
|
@ -0,0 +1,547 @@
|
|||
import os
|
||||
from dataclasses import dataclass
|
||||
from datetime import datetime
|
||||
import litellm
|
||||
|
||||
from litellm.integrations.custom_logger import CustomLogger
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.types.services import ServiceLoggerPayload
|
||||
from typing import Union, Optional, TYPE_CHECKING, Any
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from opentelemetry.trace import Span as _Span
|
||||
from litellm.proxy.proxy_server import UserAPIKeyAuth as _UserAPIKeyAuth
|
||||
|
||||
Span = _Span
|
||||
UserAPIKeyAuth = _UserAPIKeyAuth
|
||||
else:
|
||||
Span = Any
|
||||
UserAPIKeyAuth = Any
|
||||
|
||||
|
||||
LITELLM_TRACER_NAME = os.getenv("OTEL_TRACER_NAME", "litellm")
|
||||
LITELLM_RESOURCE = {
|
||||
"service.name": os.getenv("OTEL_SERVICE_NAME", "litellm"),
|
||||
}
|
||||
RAW_REQUEST_SPAN_NAME = "raw_gen_ai_request"
|
||||
LITELLM_REQUEST_SPAN_NAME = "litellm_request"
|
||||
|
||||
|
||||
@dataclass
|
||||
class OpenTelemetryConfig:
|
||||
from opentelemetry.sdk.trace.export import SpanExporter
|
||||
|
||||
exporter: str | SpanExporter = "console"
|
||||
endpoint: Optional[str] = None
|
||||
headers: Optional[str] = None
|
||||
|
||||
@classmethod
|
||||
def from_env(cls):
|
||||
"""
|
||||
OTEL_HEADERS=x-honeycomb-team=B85YgLm9****
|
||||
OTEL_EXPORTER="otlp_http"
|
||||
OTEL_ENDPOINT="https://api.honeycomb.io/v1/traces"
|
||||
|
||||
OTEL_HEADERS gets sent as headers = {"x-honeycomb-team": "B85YgLm96******"}
|
||||
"""
|
||||
return cls(
|
||||
exporter=os.getenv("OTEL_EXPORTER", "console"),
|
||||
endpoint=os.getenv("OTEL_ENDPOINT"),
|
||||
headers=os.getenv(
|
||||
"OTEL_HEADERS"
|
||||
), # example: OTEL_HEADERS=x-honeycomb-team=B85YgLm96VGdFisfJVme1H"
|
||||
)
|
||||
|
||||
|
||||
class OpenTelemetry(CustomLogger):
|
||||
def __init__(self, config=OpenTelemetryConfig.from_env()):
|
||||
from opentelemetry import trace
|
||||
from opentelemetry.sdk.resources import Resource
|
||||
from opentelemetry.sdk.trace import TracerProvider
|
||||
|
||||
self.config = config
|
||||
self.OTEL_EXPORTER = self.config.exporter
|
||||
self.OTEL_ENDPOINT = self.config.endpoint
|
||||
self.OTEL_HEADERS = self.config.headers
|
||||
provider = TracerProvider(resource=Resource(attributes=LITELLM_RESOURCE))
|
||||
provider.add_span_processor(self._get_span_processor())
|
||||
|
||||
trace.set_tracer_provider(provider)
|
||||
self.tracer = trace.get_tracer(LITELLM_TRACER_NAME)
|
||||
|
||||
_debug_otel = str(os.getenv("DEBUG_OTEL", "False")).lower()
|
||||
|
||||
if _debug_otel == "true":
|
||||
# Set up logging
|
||||
import logging
|
||||
|
||||
logging.basicConfig(level=logging.DEBUG)
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
# Enable OpenTelemetry logging
|
||||
otel_exporter_logger = logging.getLogger("opentelemetry.sdk.trace.export")
|
||||
otel_exporter_logger.setLevel(logging.DEBUG)
|
||||
|
||||
def log_success_event(self, kwargs, response_obj, start_time, end_time):
|
||||
self._handle_sucess(kwargs, response_obj, start_time, end_time)
|
||||
|
||||
def log_failure_event(self, kwargs, response_obj, start_time, end_time):
|
||||
self._handle_failure(kwargs, response_obj, start_time, end_time)
|
||||
|
||||
async def async_log_success_event(self, kwargs, response_obj, start_time, end_time):
|
||||
self._handle_sucess(kwargs, response_obj, start_time, end_time)
|
||||
|
||||
async def async_log_failure_event(self, kwargs, response_obj, start_time, end_time):
|
||||
self._handle_failure(kwargs, response_obj, start_time, end_time)
|
||||
|
||||
async def async_service_success_hook(
|
||||
self,
|
||||
payload: ServiceLoggerPayload,
|
||||
parent_otel_span: Optional[Span] = None,
|
||||
start_time: Optional[datetime] = None,
|
||||
end_time: Optional[datetime] = None,
|
||||
):
|
||||
from opentelemetry import trace
|
||||
from datetime import datetime
|
||||
from opentelemetry.trace import Status, StatusCode
|
||||
|
||||
_start_time_ns = start_time
|
||||
_end_time_ns = end_time
|
||||
|
||||
if isinstance(start_time, float):
|
||||
_start_time_ns = int(int(start_time) * 1e9)
|
||||
else:
|
||||
_start_time_ns = self._to_ns(start_time)
|
||||
|
||||
if isinstance(end_time, float):
|
||||
_end_time_ns = int(int(end_time) * 1e9)
|
||||
else:
|
||||
_end_time_ns = self._to_ns(end_time)
|
||||
|
||||
if parent_otel_span is not None:
|
||||
_span_name = payload.service
|
||||
service_logging_span = self.tracer.start_span(
|
||||
name=_span_name,
|
||||
context=trace.set_span_in_context(parent_otel_span),
|
||||
start_time=_start_time_ns,
|
||||
)
|
||||
service_logging_span.set_attribute(key="call_type", value=payload.call_type)
|
||||
service_logging_span.set_attribute(
|
||||
key="service", value=payload.service.value
|
||||
)
|
||||
service_logging_span.set_status(Status(StatusCode.OK))
|
||||
service_logging_span.end(end_time=_end_time_ns)
|
||||
|
||||
async def async_service_failure_hook(
|
||||
self,
|
||||
payload: ServiceLoggerPayload,
|
||||
parent_otel_span: Optional[Span] = None,
|
||||
start_time: Optional[datetime] = None,
|
||||
end_time: Optional[datetime] = None,
|
||||
):
|
||||
from opentelemetry import trace
|
||||
from datetime import datetime
|
||||
from opentelemetry.trace import Status, StatusCode
|
||||
|
||||
_start_time_ns = start_time
|
||||
_end_time_ns = end_time
|
||||
|
||||
if isinstance(start_time, float):
|
||||
_start_time_ns = int(int(start_time) * 1e9)
|
||||
else:
|
||||
_start_time_ns = self._to_ns(start_time)
|
||||
|
||||
if isinstance(end_time, float):
|
||||
_end_time_ns = int(int(end_time) * 1e9)
|
||||
else:
|
||||
_end_time_ns = self._to_ns(end_time)
|
||||
|
||||
if parent_otel_span is not None:
|
||||
_span_name = payload.service
|
||||
service_logging_span = self.tracer.start_span(
|
||||
name=_span_name,
|
||||
context=trace.set_span_in_context(parent_otel_span),
|
||||
start_time=_start_time_ns,
|
||||
)
|
||||
service_logging_span.set_attribute(key="call_type", value=payload.call_type)
|
||||
service_logging_span.set_attribute(
|
||||
key="service", value=payload.service.value
|
||||
)
|
||||
service_logging_span.set_status(Status(StatusCode.ERROR))
|
||||
service_logging_span.end(end_time=_end_time_ns)
|
||||
|
||||
async def async_post_call_failure_hook(
|
||||
self, original_exception: Exception, user_api_key_dict: UserAPIKeyAuth
|
||||
):
|
||||
from opentelemetry.trace import Status, StatusCode
|
||||
from opentelemetry import trace
|
||||
|
||||
parent_otel_span = user_api_key_dict.parent_otel_span
|
||||
if parent_otel_span is not None:
|
||||
parent_otel_span.set_status(Status(StatusCode.ERROR))
|
||||
_span_name = "Failed Proxy Server Request"
|
||||
|
||||
# Exception Logging Child Span
|
||||
exception_logging_span = self.tracer.start_span(
|
||||
name=_span_name,
|
||||
context=trace.set_span_in_context(parent_otel_span),
|
||||
)
|
||||
exception_logging_span.set_attribute(
|
||||
key="exception", value=str(original_exception)
|
||||
)
|
||||
exception_logging_span.set_status(Status(StatusCode.ERROR))
|
||||
exception_logging_span.end(end_time=self._to_ns(datetime.now()))
|
||||
|
||||
# End Parent OTEL Sspan
|
||||
parent_otel_span.end(end_time=self._to_ns(datetime.now()))
|
||||
|
||||
def _handle_sucess(self, kwargs, response_obj, start_time, end_time):
|
||||
from opentelemetry.trace import Status, StatusCode
|
||||
from opentelemetry import trace
|
||||
|
||||
verbose_logger.debug(
|
||||
"OpenTelemetry Logger: Logging kwargs: %s, OTEL config settings=%s",
|
||||
kwargs,
|
||||
self.config,
|
||||
)
|
||||
_parent_context, parent_otel_span = self._get_span_context(kwargs)
|
||||
|
||||
# Span 1: Requst sent to litellm SDK
|
||||
span = self.tracer.start_span(
|
||||
name=self._get_span_name(kwargs),
|
||||
start_time=self._to_ns(start_time),
|
||||
context=_parent_context,
|
||||
)
|
||||
span.set_status(Status(StatusCode.OK))
|
||||
self.set_attributes(span, kwargs, response_obj)
|
||||
|
||||
if litellm.turn_off_message_logging is True:
|
||||
pass
|
||||
else:
|
||||
# Span 2: Raw Request / Response to LLM
|
||||
raw_request_span = self.tracer.start_span(
|
||||
name=RAW_REQUEST_SPAN_NAME,
|
||||
start_time=self._to_ns(start_time),
|
||||
context=trace.set_span_in_context(span),
|
||||
)
|
||||
|
||||
raw_request_span.set_status(Status(StatusCode.OK))
|
||||
self.set_raw_request_attributes(raw_request_span, kwargs, response_obj)
|
||||
raw_request_span.end(end_time=self._to_ns(end_time))
|
||||
|
||||
span.end(end_time=self._to_ns(end_time))
|
||||
|
||||
if parent_otel_span is not None:
|
||||
parent_otel_span.end(end_time=self._to_ns(datetime.now()))
|
||||
|
||||
def _handle_failure(self, kwargs, response_obj, start_time, end_time):
|
||||
from opentelemetry.trace import Status, StatusCode
|
||||
|
||||
span = self.tracer.start_span(
|
||||
name=self._get_span_name(kwargs),
|
||||
start_time=self._to_ns(start_time),
|
||||
context=self._get_span_context(kwargs),
|
||||
)
|
||||
span.set_status(Status(StatusCode.ERROR))
|
||||
self.set_attributes(span, kwargs, response_obj)
|
||||
span.end(end_time=self._to_ns(end_time))
|
||||
|
||||
def set_tools_attributes(self, span: Span, tools):
|
||||
from opentelemetry.semconv.ai import SpanAttributes
|
||||
import json
|
||||
|
||||
if not tools:
|
||||
return
|
||||
|
||||
try:
|
||||
for i, tool in enumerate(tools):
|
||||
function = tool.get("function")
|
||||
if not function:
|
||||
continue
|
||||
|
||||
prefix = f"{SpanAttributes.LLM_REQUEST_FUNCTIONS}.{i}"
|
||||
span.set_attribute(f"{prefix}.name", function.get("name"))
|
||||
span.set_attribute(f"{prefix}.description", function.get("description"))
|
||||
span.set_attribute(
|
||||
f"{prefix}.parameters", json.dumps(function.get("parameters"))
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_logger.error(
|
||||
"OpenTelemetry: Error setting tools attributes: %s", str(e)
|
||||
)
|
||||
pass
|
||||
|
||||
def set_attributes(self, span: Span, kwargs, response_obj):
|
||||
from opentelemetry.semconv.ai import SpanAttributes
|
||||
|
||||
optional_params = kwargs.get("optional_params", {})
|
||||
litellm_params = kwargs.get("litellm_params", {}) or {}
|
||||
|
||||
# https://github.com/open-telemetry/semantic-conventions/blob/main/model/registry/gen-ai.yaml
|
||||
# Following Conventions here: https://github.com/open-telemetry/semantic-conventions/blob/main/docs/gen-ai/llm-spans.md
|
||||
|
||||
#############################################
|
||||
########## LLM Request Attributes ###########
|
||||
#############################################
|
||||
|
||||
# The name of the LLM a request is being made to
|
||||
if kwargs.get("model"):
|
||||
span.set_attribute(SpanAttributes.LLM_REQUEST_MODEL, kwargs.get("model"))
|
||||
|
||||
# The Generative AI Provider: Azure, OpenAI, etc.
|
||||
span.set_attribute(
|
||||
SpanAttributes.LLM_SYSTEM,
|
||||
litellm_params.get("custom_llm_provider", "Unknown"),
|
||||
)
|
||||
|
||||
# The maximum number of tokens the LLM generates for a request.
|
||||
if optional_params.get("max_tokens"):
|
||||
span.set_attribute(
|
||||
SpanAttributes.LLM_REQUEST_MAX_TOKENS, optional_params.get("max_tokens")
|
||||
)
|
||||
|
||||
# The temperature setting for the LLM request.
|
||||
if optional_params.get("temperature"):
|
||||
span.set_attribute(
|
||||
SpanAttributes.LLM_REQUEST_TEMPERATURE,
|
||||
optional_params.get("temperature"),
|
||||
)
|
||||
|
||||
# The top_p sampling setting for the LLM request.
|
||||
if optional_params.get("top_p"):
|
||||
span.set_attribute(
|
||||
SpanAttributes.LLM_REQUEST_TOP_P, optional_params.get("top_p")
|
||||
)
|
||||
|
||||
span.set_attribute(
|
||||
SpanAttributes.LLM_IS_STREAMING, optional_params.get("stream", False)
|
||||
)
|
||||
|
||||
if optional_params.get("tools"):
|
||||
tools = optional_params["tools"]
|
||||
self.set_tools_attributes(span, tools)
|
||||
|
||||
if optional_params.get("user"):
|
||||
span.set_attribute(SpanAttributes.LLM_USER, optional_params.get("user"))
|
||||
|
||||
if kwargs.get("messages"):
|
||||
for idx, prompt in enumerate(kwargs.get("messages")):
|
||||
if prompt.get("role"):
|
||||
span.set_attribute(
|
||||
f"{SpanAttributes.LLM_PROMPTS}.{idx}.role",
|
||||
prompt.get("role"),
|
||||
)
|
||||
|
||||
if prompt.get("content"):
|
||||
if not isinstance(prompt.get("content"), str):
|
||||
prompt["content"] = str(prompt.get("content"))
|
||||
span.set_attribute(
|
||||
f"{SpanAttributes.LLM_PROMPTS}.{idx}.content",
|
||||
prompt.get("content"),
|
||||
)
|
||||
#############################################
|
||||
########## LLM Response Attributes ##########
|
||||
#############################################
|
||||
if response_obj.get("choices"):
|
||||
for idx, choice in enumerate(response_obj.get("choices")):
|
||||
if choice.get("finish_reason"):
|
||||
span.set_attribute(
|
||||
f"{SpanAttributes.LLM_COMPLETIONS}.{idx}.finish_reason",
|
||||
choice.get("finish_reason"),
|
||||
)
|
||||
if choice.get("message"):
|
||||
if choice.get("message").get("role"):
|
||||
span.set_attribute(
|
||||
f"{SpanAttributes.LLM_COMPLETIONS}.{idx}.role",
|
||||
choice.get("message").get("role"),
|
||||
)
|
||||
if choice.get("message").get("content"):
|
||||
if not isinstance(choice.get("message").get("content"), str):
|
||||
choice["message"]["content"] = str(
|
||||
choice.get("message").get("content")
|
||||
)
|
||||
span.set_attribute(
|
||||
f"{SpanAttributes.LLM_COMPLETIONS}.{idx}.content",
|
||||
choice.get("message").get("content"),
|
||||
)
|
||||
|
||||
message = choice.get("message")
|
||||
tool_calls = message.get("tool_calls")
|
||||
if tool_calls:
|
||||
span.set_attribute(
|
||||
f"{SpanAttributes.LLM_COMPLETIONS}.{idx}.function_call.name",
|
||||
tool_calls[0].get("function").get("name"),
|
||||
)
|
||||
span.set_attribute(
|
||||
f"{SpanAttributes.LLM_COMPLETIONS}.{idx}.function_call.arguments",
|
||||
tool_calls[0].get("function").get("arguments"),
|
||||
)
|
||||
|
||||
# The unique identifier for the completion.
|
||||
if response_obj.get("id"):
|
||||
span.set_attribute("gen_ai.response.id", response_obj.get("id"))
|
||||
|
||||
# The model used to generate the response.
|
||||
if response_obj.get("model"):
|
||||
span.set_attribute(
|
||||
SpanAttributes.LLM_RESPONSE_MODEL, response_obj.get("model")
|
||||
)
|
||||
|
||||
usage = response_obj.get("usage")
|
||||
if usage:
|
||||
span.set_attribute(
|
||||
SpanAttributes.LLM_USAGE_TOTAL_TOKENS,
|
||||
usage.get("total_tokens"),
|
||||
)
|
||||
|
||||
# The number of tokens used in the LLM response (completion).
|
||||
span.set_attribute(
|
||||
SpanAttributes.LLM_USAGE_COMPLETION_TOKENS,
|
||||
usage.get("completion_tokens"),
|
||||
)
|
||||
|
||||
# The number of tokens used in the LLM prompt.
|
||||
span.set_attribute(
|
||||
SpanAttributes.LLM_USAGE_PROMPT_TOKENS,
|
||||
usage.get("prompt_tokens"),
|
||||
)
|
||||
|
||||
def set_raw_request_attributes(self, span: Span, kwargs, response_obj):
|
||||
from opentelemetry.semconv.ai import SpanAttributes
|
||||
|
||||
optional_params = kwargs.get("optional_params", {})
|
||||
litellm_params = kwargs.get("litellm_params", {}) or {}
|
||||
custom_llm_provider = litellm_params.get("custom_llm_provider", "Unknown")
|
||||
|
||||
_raw_response = kwargs.get("original_response")
|
||||
_additional_args = kwargs.get("additional_args", {}) or {}
|
||||
complete_input_dict = _additional_args.get("complete_input_dict")
|
||||
#############################################
|
||||
########## LLM Request Attributes ###########
|
||||
#############################################
|
||||
|
||||
# OTEL Attributes for the RAW Request to https://docs.anthropic.com/en/api/messages
|
||||
if complete_input_dict:
|
||||
for param, val in complete_input_dict.items():
|
||||
if not isinstance(val, str):
|
||||
val = str(val)
|
||||
span.set_attribute(
|
||||
f"llm.{custom_llm_provider}.{param}",
|
||||
val,
|
||||
)
|
||||
|
||||
#############################################
|
||||
########## LLM Response Attributes ##########
|
||||
#############################################
|
||||
if _raw_response:
|
||||
# cast sr -> dict
|
||||
import json
|
||||
|
||||
_raw_response = json.loads(_raw_response)
|
||||
for param, val in _raw_response.items():
|
||||
if not isinstance(val, str):
|
||||
val = str(val)
|
||||
span.set_attribute(
|
||||
f"llm.{custom_llm_provider}.{param}",
|
||||
val,
|
||||
)
|
||||
|
||||
pass
|
||||
|
||||
def _to_ns(self, dt):
|
||||
return int(dt.timestamp() * 1e9)
|
||||
|
||||
def _get_span_name(self, kwargs):
|
||||
return LITELLM_REQUEST_SPAN_NAME
|
||||
|
||||
def _get_span_context(self, kwargs):
|
||||
from opentelemetry.trace.propagation.tracecontext import (
|
||||
TraceContextTextMapPropagator,
|
||||
)
|
||||
from opentelemetry import trace
|
||||
|
||||
litellm_params = kwargs.get("litellm_params", {}) or {}
|
||||
proxy_server_request = litellm_params.get("proxy_server_request", {}) or {}
|
||||
headers = proxy_server_request.get("headers", {}) or {}
|
||||
traceparent = headers.get("traceparent", None)
|
||||
_metadata = litellm_params.get("metadata", {}) or {}
|
||||
parent_otel_span = _metadata.get("litellm_parent_otel_span", None)
|
||||
|
||||
"""
|
||||
Two way to use parents in opentelemetry
|
||||
- using the traceparent header
|
||||
- using the parent_otel_span in the [metadata][parent_otel_span]
|
||||
"""
|
||||
if parent_otel_span is not None:
|
||||
return trace.set_span_in_context(parent_otel_span), parent_otel_span
|
||||
|
||||
if traceparent is None:
|
||||
return None, None
|
||||
else:
|
||||
carrier = {"traceparent": traceparent}
|
||||
return TraceContextTextMapPropagator().extract(carrier=carrier), None
|
||||
|
||||
def _get_span_processor(self):
|
||||
from opentelemetry.sdk.trace.export import (
|
||||
SpanExporter,
|
||||
SimpleSpanProcessor,
|
||||
BatchSpanProcessor,
|
||||
ConsoleSpanExporter,
|
||||
)
|
||||
from opentelemetry.exporter.otlp.proto.http.trace_exporter import (
|
||||
OTLPSpanExporter as OTLPSpanExporterHTTP,
|
||||
)
|
||||
from opentelemetry.exporter.otlp.proto.grpc.trace_exporter import (
|
||||
OTLPSpanExporter as OTLPSpanExporterGRPC,
|
||||
)
|
||||
|
||||
verbose_logger.debug(
|
||||
"OpenTelemetry Logger, initializing span processor \nself.OTEL_EXPORTER: %s\nself.OTEL_ENDPOINT: %s\nself.OTEL_HEADERS: %s",
|
||||
self.OTEL_EXPORTER,
|
||||
self.OTEL_ENDPOINT,
|
||||
self.OTEL_HEADERS,
|
||||
)
|
||||
_split_otel_headers = {}
|
||||
if self.OTEL_HEADERS is not None and isinstance(self.OTEL_HEADERS, str):
|
||||
_split_otel_headers = self.OTEL_HEADERS.split("=")
|
||||
_split_otel_headers = {_split_otel_headers[0]: _split_otel_headers[1]}
|
||||
|
||||
if isinstance(self.OTEL_EXPORTER, SpanExporter):
|
||||
verbose_logger.debug(
|
||||
"OpenTelemetry: intiializing SpanExporter. Value of OTEL_EXPORTER: %s",
|
||||
self.OTEL_EXPORTER,
|
||||
)
|
||||
return SimpleSpanProcessor(self.OTEL_EXPORTER)
|
||||
|
||||
if self.OTEL_EXPORTER == "console":
|
||||
verbose_logger.debug(
|
||||
"OpenTelemetry: intiializing console exporter. Value of OTEL_EXPORTER: %s",
|
||||
self.OTEL_EXPORTER,
|
||||
)
|
||||
return BatchSpanProcessor(ConsoleSpanExporter())
|
||||
elif self.OTEL_EXPORTER == "otlp_http":
|
||||
verbose_logger.debug(
|
||||
"OpenTelemetry: intiializing http exporter. Value of OTEL_EXPORTER: %s",
|
||||
self.OTEL_EXPORTER,
|
||||
)
|
||||
return BatchSpanProcessor(
|
||||
OTLPSpanExporterHTTP(
|
||||
endpoint=self.OTEL_ENDPOINT, headers=_split_otel_headers
|
||||
)
|
||||
)
|
||||
elif self.OTEL_EXPORTER == "otlp_grpc":
|
||||
verbose_logger.debug(
|
||||
"OpenTelemetry: intiializing grpc exporter. Value of OTEL_EXPORTER: %s",
|
||||
self.OTEL_EXPORTER,
|
||||
)
|
||||
return BatchSpanProcessor(
|
||||
OTLPSpanExporterGRPC(
|
||||
endpoint=self.OTEL_ENDPOINT, headers=_split_otel_headers
|
||||
)
|
||||
)
|
||||
else:
|
||||
verbose_logger.debug(
|
||||
"OpenTelemetry: intiializing console exporter. Value of OTEL_EXPORTER: %s",
|
||||
self.OTEL_EXPORTER,
|
||||
)
|
||||
return BatchSpanProcessor(ConsoleSpanExporter())
|
||||
|
|
@ -109,8 +109,8 @@ class PrometheusLogger:
|
|||
end_user_id, user_api_key, model, user_api_team, user_id
|
||||
).inc()
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.debug(
|
||||
f"prometheus Layer Error - {str(e)}\n{traceback.format_exc()}"
|
||||
verbose_logger.error(
|
||||
"prometheus Layer Error(): Exception occured - {}".format(str(e))
|
||||
)
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
pass
|
||||
|
|
|
|||
|
|
@ -180,6 +180,5 @@ class S3Logger:
|
|||
print_verbose(f"s3 Layer Logging - final response object: {response_obj}")
|
||||
return response
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.debug(f"s3 Layer Error - {str(e)}\n{traceback.format_exc()}")
|
||||
pass
|
||||
|
|
|
|||
|
|
@ -326,8 +326,8 @@ class SlackAlerting(CustomLogger):
|
|||
end_time=end_time,
|
||||
)
|
||||
)
|
||||
if litellm.turn_off_message_logging:
|
||||
messages = "Message not logged. `litellm.turn_off_message_logging=True`."
|
||||
if litellm.turn_off_message_logging or litellm.redact_messages_in_exceptions:
|
||||
messages = "Message not logged. litellm.redact_messages_in_exceptions=True"
|
||||
request_info = f"\nRequest Model: `{model}`\nAPI Base: `{api_base}`\nMessages: `{messages}`"
|
||||
slow_message = f"`Responses are slow - {round(time_difference_float,2)}s response time > Alerting threshold: {self.alerting_threshold}s`"
|
||||
if time_difference_float > self.alerting_threshold:
|
||||
|
|
@ -537,7 +537,7 @@ class SlackAlerting(CustomLogger):
|
|||
cache_list=combined_metrics_cache_keys
|
||||
)
|
||||
|
||||
message += f"\n\nNext Run is in: `{time.time() + self.alerting_args.daily_report_frequency}`s"
|
||||
message += f"\n\nNext Run is at: `{time.time() + self.alerting_args.daily_report_frequency}`s"
|
||||
|
||||
# send alert
|
||||
await self.send_alert(message=message, level="Low", alert_type="daily_reports")
|
||||
|
|
@ -567,9 +567,12 @@ class SlackAlerting(CustomLogger):
|
|||
except:
|
||||
messages = ""
|
||||
|
||||
if litellm.turn_off_message_logging:
|
||||
if (
|
||||
litellm.turn_off_message_logging
|
||||
or litellm.redact_messages_in_exceptions
|
||||
):
|
||||
messages = (
|
||||
"Message not logged. `litellm.turn_off_message_logging=True`."
|
||||
"Message not logged. litellm.redact_messages_in_exceptions=True"
|
||||
)
|
||||
request_info = f"\nRequest Model: `{model}`\nMessages: `{messages}`"
|
||||
else:
|
||||
|
|
@ -1204,7 +1207,9 @@ Model Info:
|
|||
return False
|
||||
from litellm.proxy.proxy_server import premium_user, prisma_client
|
||||
|
||||
email_logo_url = os.getenv("SMTP_SENDER_LOGO", None)
|
||||
email_logo_url = os.getenv(
|
||||
"SMTP_SENDER_LOGO", os.getenv("EMAIL_LOGO_URL", None)
|
||||
)
|
||||
email_support_contact = os.getenv("EMAIL_SUPPORT_CONTACT", None)
|
||||
await self._check_if_using_premium_email_feature(
|
||||
premium_user, email_logo_url, email_support_contact
|
||||
|
|
@ -1304,7 +1309,9 @@ Model Info:
|
|||
|
||||
from litellm.proxy.proxy_server import premium_user, prisma_client
|
||||
|
||||
email_logo_url = os.getenv("SMTP_SENDER_LOGO", None)
|
||||
email_logo_url = os.getenv(
|
||||
"SMTP_SENDER_LOGO", os.getenv("EMAIL_LOGO_URL", None)
|
||||
)
|
||||
email_support_contact = os.getenv("EMAIL_SUPPORT_CONTACT", None)
|
||||
await self._check_if_using_premium_email_feature(
|
||||
premium_user, email_logo_url, email_support_contact
|
||||
|
|
|
|||
|
|
@ -110,6 +110,5 @@ class Supabase:
|
|||
)
|
||||
|
||||
except:
|
||||
# traceback.print_exc()
|
||||
print_verbose(f"Supabase Logging Error - {traceback.format_exc()}")
|
||||
pass
|
||||
|
|
|
|||
0
litellm/integrations/test_httpx.py
Normal file
|
|
@ -9,6 +9,7 @@ class TraceloopLogger:
|
|||
from traceloop.sdk.tracing.tracing import TracerWrapper
|
||||
from traceloop.sdk import Traceloop
|
||||
from traceloop.sdk.instruments import Instruments
|
||||
from opentelemetry.sdk.trace.export import ConsoleSpanExporter
|
||||
except ModuleNotFoundError as e:
|
||||
verbose_logger.error(
|
||||
f"Traceloop not installed, try running 'pip install traceloop-sdk' to fix this error: {e}\n{traceback.format_exc()}"
|
||||
|
|
@ -17,13 +18,6 @@ class TraceloopLogger:
|
|||
Traceloop.init(
|
||||
app_name="Litellm-Server",
|
||||
disable_batch=True,
|
||||
instruments=[
|
||||
Instruments.CHROMA,
|
||||
Instruments.PINECONE,
|
||||
Instruments.WEAVIATE,
|
||||
Instruments.LLAMA_INDEX,
|
||||
Instruments.LANGCHAIN,
|
||||
],
|
||||
)
|
||||
self.tracer_wrapper = TracerWrapper()
|
||||
|
||||
|
|
@ -50,6 +44,8 @@ class TraceloopLogger:
|
|||
tracer = self.tracer_wrapper.get_tracer()
|
||||
|
||||
optional_params = kwargs.get("optional_params", {})
|
||||
start_time = int(start_time.timestamp())
|
||||
end_time = int(end_time.timestamp())
|
||||
span = tracer.start_span(
|
||||
"litellm.completion", kind=SpanKind.CLIENT, start_time=start_time
|
||||
)
|
||||
|
|
|
|||
|
|
@ -217,6 +217,5 @@ class WeightsBiasesLogger:
|
|||
f"W&B Logging Logging - final response object: {response_obj}"
|
||||
)
|
||||
except:
|
||||
# traceback.print_exc()
|
||||
print_verbose(f"W&B Logging Layer Error - {traceback.format_exc()}")
|
||||
pass
|
||||
|
|
|
|||
|
|
@ -3,6 +3,7 @@ import json
|
|||
from enum import Enum
|
||||
import requests, copy # type: ignore
|
||||
import time
|
||||
from functools import partial
|
||||
from typing import Callable, Optional, List, Union
|
||||
from litellm.utils import ModelResponse, Usage, map_finish_reason, CustomStreamWrapper
|
||||
import litellm
|
||||
|
|
@ -160,6 +161,36 @@ def validate_environment(api_key, user_headers):
|
|||
return headers
|
||||
|
||||
|
||||
async def make_call(
|
||||
client: Optional[AsyncHTTPHandler],
|
||||
api_base: str,
|
||||
headers: dict,
|
||||
data: str,
|
||||
model: str,
|
||||
messages: list,
|
||||
logging_obj,
|
||||
):
|
||||
if client is None:
|
||||
client = AsyncHTTPHandler() # Create a new client if none provided
|
||||
|
||||
response = await client.post(api_base, headers=headers, data=data, stream=True)
|
||||
|
||||
if response.status_code != 200:
|
||||
raise AnthropicError(status_code=response.status_code, message=response.text)
|
||||
|
||||
completion_stream = response.aiter_lines()
|
||||
|
||||
# LOGGING
|
||||
logging_obj.post_call(
|
||||
input=messages,
|
||||
api_key="",
|
||||
original_response=completion_stream, # Pass the completion stream for logging
|
||||
additional_args={"complete_input_dict": data},
|
||||
)
|
||||
|
||||
return completion_stream
|
||||
|
||||
|
||||
class AnthropicChatCompletion(BaseLLM):
|
||||
def __init__(self) -> None:
|
||||
super().__init__()
|
||||
|
|
@ -379,22 +410,34 @@ class AnthropicChatCompletion(BaseLLM):
|
|||
logger_fn=None,
|
||||
headers={},
|
||||
):
|
||||
|
||||
async_handler = AsyncHTTPHandler(
|
||||
timeout=httpx.Timeout(timeout=600.0, connect=20.0)
|
||||
)
|
||||
data["stream"] = True
|
||||
response = await async_handler.post(api_base, headers=headers, json=data)
|
||||
# async_handler = AsyncHTTPHandler(
|
||||
# timeout=httpx.Timeout(timeout=600.0, connect=20.0)
|
||||
# )
|
||||
|
||||
if response.status_code != 200:
|
||||
raise AnthropicError(
|
||||
status_code=response.status_code, message=response.text
|
||||
)
|
||||
# response = await async_handler.post(
|
||||
# api_base, headers=headers, json=data, stream=True
|
||||
# )
|
||||
|
||||
completion_stream = response.aiter_lines()
|
||||
# if response.status_code != 200:
|
||||
# raise AnthropicError(
|
||||
# status_code=response.status_code, message=response.text
|
||||
# )
|
||||
|
||||
# completion_stream = response.aiter_lines()
|
||||
|
||||
streamwrapper = CustomStreamWrapper(
|
||||
completion_stream=completion_stream,
|
||||
completion_stream=None,
|
||||
make_call=partial(
|
||||
make_call,
|
||||
client=None,
|
||||
api_base=api_base,
|
||||
headers=headers,
|
||||
data=json.dumps(data),
|
||||
model=model,
|
||||
messages=messages,
|
||||
logging_obj=logging_obj,
|
||||
),
|
||||
model=model,
|
||||
custom_llm_provider="anthropic",
|
||||
logging_obj=logging_obj,
|
||||
|
|
|
|||
|
|
@ -38,6 +38,8 @@ from .prompt_templates.factory import (
|
|||
extract_between_tags,
|
||||
parse_xml_params,
|
||||
contains_tag,
|
||||
_bedrock_converse_messages_pt,
|
||||
_bedrock_tools_pt,
|
||||
)
|
||||
from litellm.llms.custom_httpx.http_handler import AsyncHTTPHandler, HTTPHandler
|
||||
from .base import BaseLLM
|
||||
|
|
@ -45,6 +47,12 @@ import httpx # type: ignore
|
|||
from .bedrock import BedrockError, convert_messages_to_prompt, ModelResponseIterator
|
||||
from litellm.types.llms.bedrock import *
|
||||
import urllib.parse
|
||||
from litellm.types.llms.openai import (
|
||||
ChatCompletionResponseMessage,
|
||||
ChatCompletionToolCallChunk,
|
||||
ChatCompletionToolCallFunctionChunk,
|
||||
ChatCompletionDeltaChunk,
|
||||
)
|
||||
|
||||
|
||||
class AmazonCohereChatConfig:
|
||||
|
|
@ -118,6 +126,8 @@ class AmazonCohereChatConfig:
|
|||
"presence_penalty",
|
||||
"seed",
|
||||
"stop",
|
||||
"tools",
|
||||
"tool_choice",
|
||||
]
|
||||
|
||||
def map_openai_params(
|
||||
|
|
@ -169,7 +179,38 @@ async def make_call(
|
|||
logging_obj.post_call(
|
||||
input=messages,
|
||||
api_key="",
|
||||
original_response=completion_stream, # Pass the completion stream for logging
|
||||
original_response="first stream response received",
|
||||
additional_args={"complete_input_dict": data},
|
||||
)
|
||||
|
||||
return completion_stream
|
||||
|
||||
|
||||
def make_sync_call(
|
||||
client: Optional[HTTPHandler],
|
||||
api_base: str,
|
||||
headers: dict,
|
||||
data: str,
|
||||
model: str,
|
||||
messages: list,
|
||||
logging_obj,
|
||||
):
|
||||
if client is None:
|
||||
client = HTTPHandler() # Create a new client if none provided
|
||||
|
||||
response = client.post(api_base, headers=headers, data=data, stream=True)
|
||||
|
||||
if response.status_code != 200:
|
||||
raise BedrockError(status_code=response.status_code, message=response.read())
|
||||
|
||||
decoder = AWSEventStreamDecoder(model=model)
|
||||
completion_stream = decoder.iter_bytes(response.iter_bytes(chunk_size=1024))
|
||||
|
||||
# LOGGING
|
||||
logging_obj.post_call(
|
||||
input=messages,
|
||||
api_key="",
|
||||
original_response="first stream response received",
|
||||
additional_args={"complete_input_dict": data},
|
||||
)
|
||||
|
||||
|
|
@ -284,7 +325,11 @@ class BedrockLLM(BaseLLM):
|
|||
) = params_to_check
|
||||
|
||||
### CHECK STS ###
|
||||
if aws_web_identity_token is not None and aws_role_name is not None and aws_session_name is not None:
|
||||
if (
|
||||
aws_web_identity_token is not None
|
||||
and aws_role_name is not None
|
||||
and aws_session_name is not None
|
||||
):
|
||||
oidc_token = get_secret(aws_web_identity_token)
|
||||
|
||||
if oidc_token is None:
|
||||
|
|
@ -293,9 +338,7 @@ class BedrockLLM(BaseLLM):
|
|||
status_code=401,
|
||||
)
|
||||
|
||||
sts_client = boto3.client(
|
||||
"sts"
|
||||
)
|
||||
sts_client = boto3.client("sts")
|
||||
|
||||
# https://docs.aws.amazon.com/STS/latest/APIReference/API_AssumeRoleWithWebIdentity.html
|
||||
# https://boto3.amazonaws.com/v1/documentation/api/latest/reference/services/sts/client/assume_role_with_web_identity.html
|
||||
|
|
@ -998,16 +1041,16 @@ class BedrockLLM(BaseLLM):
|
|||
if isinstance(timeout, float) or isinstance(timeout, int):
|
||||
timeout = httpx.Timeout(timeout)
|
||||
_params["timeout"] = timeout
|
||||
self.client = AsyncHTTPHandler(**_params) # type: ignore
|
||||
client = AsyncHTTPHandler(**_params) # type: ignore
|
||||
else:
|
||||
self.client = client # type: ignore
|
||||
client = client # type: ignore
|
||||
|
||||
try:
|
||||
response = await self.client.post(api_base, headers=headers, data=data) # type: ignore
|
||||
response = await client.post(api_base, headers=headers, data=data) # type: ignore
|
||||
response.raise_for_status()
|
||||
except httpx.HTTPStatusError as err:
|
||||
error_code = err.response.status_code
|
||||
raise BedrockError(status_code=error_code, message=response.text)
|
||||
raise BedrockError(status_code=error_code, message=err.response.text)
|
||||
except httpx.TimeoutException as e:
|
||||
raise BedrockError(status_code=408, message="Timeout error occurred.")
|
||||
|
||||
|
|
@ -1067,6 +1110,738 @@ class BedrockLLM(BaseLLM):
|
|||
return super().embedding(*args, **kwargs)
|
||||
|
||||
|
||||
class AmazonConverseConfig:
|
||||
"""
|
||||
Reference - https://docs.aws.amazon.com/bedrock/latest/APIReference/API_runtime_Converse.html
|
||||
#2 - https://docs.aws.amazon.com/bedrock/latest/userguide/conversation-inference.html#conversation-inference-supported-models-features
|
||||
"""
|
||||
|
||||
maxTokens: Optional[int]
|
||||
stopSequences: Optional[List[str]]
|
||||
temperature: Optional[int]
|
||||
topP: Optional[int]
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
maxTokens: Optional[int] = None,
|
||||
stopSequences: Optional[List[str]] = None,
|
||||
temperature: Optional[int] = None,
|
||||
topP: Optional[int] = None,
|
||||
) -> None:
|
||||
locals_ = locals()
|
||||
for key, value in locals_.items():
|
||||
if key != "self" and value is not None:
|
||||
setattr(self.__class__, key, value)
|
||||
|
||||
@classmethod
|
||||
def get_config(cls):
|
||||
return {
|
||||
k: v
|
||||
for k, v in cls.__dict__.items()
|
||||
if not k.startswith("__")
|
||||
and not isinstance(
|
||||
v,
|
||||
(
|
||||
types.FunctionType,
|
||||
types.BuiltinFunctionType,
|
||||
classmethod,
|
||||
staticmethod,
|
||||
),
|
||||
)
|
||||
and v is not None
|
||||
}
|
||||
|
||||
def get_supported_openai_params(self, model: str) -> List[str]:
|
||||
supported_params = [
|
||||
"max_tokens",
|
||||
"stream",
|
||||
"stream_options",
|
||||
"stop",
|
||||
"temperature",
|
||||
"top_p",
|
||||
"extra_headers",
|
||||
]
|
||||
|
||||
if (
|
||||
model.startswith("anthropic")
|
||||
or model.startswith("mistral")
|
||||
or model.startswith("cohere")
|
||||
):
|
||||
supported_params.append("tools")
|
||||
|
||||
if model.startswith("anthropic") or model.startswith("mistral"):
|
||||
# only anthropic and mistral support tool choice config. otherwise (E.g. cohere) will fail the call - https://docs.aws.amazon.com/bedrock/latest/APIReference/API_runtime_ToolChoice.html
|
||||
supported_params.append("tool_choice")
|
||||
|
||||
return supported_params
|
||||
|
||||
def map_tool_choice_values(
|
||||
self, model: str, tool_choice: Union[str, dict], drop_params: bool
|
||||
) -> Optional[ToolChoiceValuesBlock]:
|
||||
if tool_choice == "none":
|
||||
if litellm.drop_params is True or drop_params is True:
|
||||
return None
|
||||
else:
|
||||
raise litellm.utils.UnsupportedParamsError(
|
||||
message="Bedrock doesn't support tool_choice={}. To drop it from the call, set `litellm.drop_params = True.".format(
|
||||
tool_choice
|
||||
),
|
||||
status_code=400,
|
||||
)
|
||||
elif tool_choice == "required":
|
||||
return ToolChoiceValuesBlock(any={})
|
||||
elif tool_choice == "auto":
|
||||
return ToolChoiceValuesBlock(auto={})
|
||||
elif isinstance(tool_choice, dict):
|
||||
# only supported for anthropic + mistral models - https://docs.aws.amazon.com/bedrock/latest/APIReference/API_runtime_ToolChoice.html
|
||||
specific_tool = SpecificToolChoiceBlock(
|
||||
name=tool_choice.get("function", {}).get("name", "")
|
||||
)
|
||||
return ToolChoiceValuesBlock(tool=specific_tool)
|
||||
else:
|
||||
raise litellm.utils.UnsupportedParamsError(
|
||||
message="Bedrock doesn't support tool_choice={}. Supported tool_choice values=['auto', 'required', json object]. To drop it from the call, set `litellm.drop_params = True.".format(
|
||||
tool_choice
|
||||
),
|
||||
status_code=400,
|
||||
)
|
||||
|
||||
def get_supported_image_types(self) -> List[str]:
|
||||
return ["png", "jpeg", "gif", "webp"]
|
||||
|
||||
def map_openai_params(
|
||||
self,
|
||||
model: str,
|
||||
non_default_params: dict,
|
||||
optional_params: dict,
|
||||
drop_params: bool,
|
||||
) -> dict:
|
||||
for param, value in non_default_params.items():
|
||||
if param == "max_tokens":
|
||||
optional_params["maxTokens"] = value
|
||||
if param == "stream":
|
||||
optional_params["stream"] = value
|
||||
if param == "stop":
|
||||
if isinstance(value, str):
|
||||
value = [value]
|
||||
optional_params["stop_sequences"] = value
|
||||
if param == "temperature":
|
||||
optional_params["temperature"] = value
|
||||
if param == "top_p":
|
||||
optional_params["topP"] = value
|
||||
if param == "tools":
|
||||
optional_params["tools"] = value
|
||||
if param == "tool_choice":
|
||||
_tool_choice_value = self.map_tool_choice_values(
|
||||
model=model, tool_choice=value, drop_params=drop_params # type: ignore
|
||||
)
|
||||
if _tool_choice_value is not None:
|
||||
optional_params["tool_choice"] = _tool_choice_value
|
||||
return optional_params
|
||||
|
||||
|
||||
class BedrockConverseLLM(BaseLLM):
|
||||
def __init__(self) -> None:
|
||||
super().__init__()
|
||||
|
||||
def process_response(
|
||||
self,
|
||||
model: str,
|
||||
response: Union[requests.Response, httpx.Response],
|
||||
model_response: ModelResponse,
|
||||
stream: bool,
|
||||
logging_obj: Logging,
|
||||
optional_params: dict,
|
||||
api_key: str,
|
||||
data: Union[dict, str],
|
||||
messages: List,
|
||||
print_verbose,
|
||||
encoding,
|
||||
) -> Union[ModelResponse, CustomStreamWrapper]:
|
||||
|
||||
## LOGGING
|
||||
logging_obj.post_call(
|
||||
input=messages,
|
||||
api_key=api_key,
|
||||
original_response=response.text,
|
||||
additional_args={"complete_input_dict": data},
|
||||
)
|
||||
print_verbose(f"raw model_response: {response.text}")
|
||||
|
||||
## RESPONSE OBJECT
|
||||
try:
|
||||
completion_response = ConverseResponseBlock(**response.json()) # type: ignore
|
||||
except Exception as e:
|
||||
raise BedrockError(
|
||||
message="Received={}, Error converting to valid response block={}. File an issue if litellm error - https://github.com/BerriAI/litellm/issues".format(
|
||||
response.text, str(e)
|
||||
),
|
||||
status_code=422,
|
||||
)
|
||||
|
||||
"""
|
||||
Bedrock Response Object has optional message block
|
||||
|
||||
completion_response["output"].get("message", None)
|
||||
|
||||
A message block looks like this (Example 1):
|
||||
"output": {
|
||||
"message": {
|
||||
"role": "assistant",
|
||||
"content": [
|
||||
{
|
||||
"text": "Is there anything else you'd like to talk about? Perhaps I can help with some economic questions or provide some information about economic concepts?"
|
||||
}
|
||||
]
|
||||
}
|
||||
},
|
||||
(Example 2):
|
||||
"output": {
|
||||
"message": {
|
||||
"role": "assistant",
|
||||
"content": [
|
||||
{
|
||||
"toolUse": {
|
||||
"toolUseId": "tooluse_hbTgdi0CSLq_hM4P8csZJA",
|
||||
"name": "top_song",
|
||||
"input": {
|
||||
"sign": "WZPZ"
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
|
||||
"""
|
||||
message: Optional[MessageBlock] = completion_response["output"]["message"]
|
||||
chat_completion_message: ChatCompletionResponseMessage = {"role": "assistant"}
|
||||
content_str = ""
|
||||
tools: List[ChatCompletionToolCallChunk] = []
|
||||
if message is not None:
|
||||
for content in message["content"]:
|
||||
"""
|
||||
- Content is either a tool response or text
|
||||
"""
|
||||
if "text" in content:
|
||||
content_str += content["text"]
|
||||
if "toolUse" in content:
|
||||
_function_chunk = ChatCompletionToolCallFunctionChunk(
|
||||
name=content["toolUse"]["name"],
|
||||
arguments=json.dumps(content["toolUse"]["input"]),
|
||||
)
|
||||
_tool_response_chunk = ChatCompletionToolCallChunk(
|
||||
id=content["toolUse"]["toolUseId"],
|
||||
type="function",
|
||||
function=_function_chunk,
|
||||
)
|
||||
tools.append(_tool_response_chunk)
|
||||
chat_completion_message["content"] = content_str
|
||||
chat_completion_message["tool_calls"] = tools
|
||||
|
||||
## CALCULATING USAGE - bedrock returns usage in the headers
|
||||
input_tokens = completion_response["usage"]["inputTokens"]
|
||||
output_tokens = completion_response["usage"]["outputTokens"]
|
||||
total_tokens = completion_response["usage"]["totalTokens"]
|
||||
|
||||
model_response.choices = [
|
||||
litellm.Choices(
|
||||
finish_reason=map_finish_reason(completion_response["stopReason"]),
|
||||
index=0,
|
||||
message=litellm.Message(**chat_completion_message),
|
||||
)
|
||||
]
|
||||
model_response["created"] = int(time.time())
|
||||
model_response["model"] = model
|
||||
usage = Usage(
|
||||
prompt_tokens=input_tokens,
|
||||
completion_tokens=output_tokens,
|
||||
total_tokens=total_tokens,
|
||||
)
|
||||
setattr(model_response, "usage", usage)
|
||||
|
||||
return model_response
|
||||
|
||||
def encode_model_id(self, model_id: str) -> str:
|
||||
"""
|
||||
Double encode the model ID to ensure it matches the expected double-encoded format.
|
||||
Args:
|
||||
model_id (str): The model ID to encode.
|
||||
Returns:
|
||||
str: The double-encoded model ID.
|
||||
"""
|
||||
return urllib.parse.quote(model_id, safe="")
|
||||
|
||||
def get_credentials(
|
||||
self,
|
||||
aws_access_key_id: Optional[str] = None,
|
||||
aws_secret_access_key: Optional[str] = None,
|
||||
aws_region_name: Optional[str] = None,
|
||||
aws_session_name: Optional[str] = None,
|
||||
aws_profile_name: Optional[str] = None,
|
||||
aws_role_name: Optional[str] = None,
|
||||
aws_web_identity_token: Optional[str] = None,
|
||||
):
|
||||
"""
|
||||
Return a boto3.Credentials object
|
||||
"""
|
||||
import boto3
|
||||
|
||||
## CHECK IS 'os.environ/' passed in
|
||||
params_to_check: List[Optional[str]] = [
|
||||
aws_access_key_id,
|
||||
aws_secret_access_key,
|
||||
aws_region_name,
|
||||
aws_session_name,
|
||||
aws_profile_name,
|
||||
aws_role_name,
|
||||
aws_web_identity_token,
|
||||
]
|
||||
|
||||
# Iterate over parameters and update if needed
|
||||
for i, param in enumerate(params_to_check):
|
||||
if param and param.startswith("os.environ/"):
|
||||
_v = get_secret(param)
|
||||
if _v is not None and isinstance(_v, str):
|
||||
params_to_check[i] = _v
|
||||
# Assign updated values back to parameters
|
||||
(
|
||||
aws_access_key_id,
|
||||
aws_secret_access_key,
|
||||
aws_region_name,
|
||||
aws_session_name,
|
||||
aws_profile_name,
|
||||
aws_role_name,
|
||||
aws_web_identity_token,
|
||||
) = params_to_check
|
||||
|
||||
### CHECK STS ###
|
||||
if (
|
||||
aws_web_identity_token is not None
|
||||
and aws_role_name is not None
|
||||
and aws_session_name is not None
|
||||
):
|
||||
oidc_token = get_secret(aws_web_identity_token)
|
||||
|
||||
if oidc_token is None:
|
||||
raise BedrockError(
|
||||
message="OIDC token could not be retrieved from secret manager.",
|
||||
status_code=401,
|
||||
)
|
||||
|
||||
sts_client = boto3.client("sts")
|
||||
|
||||
# https://docs.aws.amazon.com/STS/latest/APIReference/API_AssumeRoleWithWebIdentity.html
|
||||
# https://boto3.amazonaws.com/v1/documentation/api/latest/reference/services/sts/client/assume_role_with_web_identity.html
|
||||
sts_response = sts_client.assume_role_with_web_identity(
|
||||
RoleArn=aws_role_name,
|
||||
RoleSessionName=aws_session_name,
|
||||
WebIdentityToken=oidc_token,
|
||||
DurationSeconds=3600,
|
||||
)
|
||||
|
||||
session = boto3.Session(
|
||||
aws_access_key_id=sts_response["Credentials"]["AccessKeyId"],
|
||||
aws_secret_access_key=sts_response["Credentials"]["SecretAccessKey"],
|
||||
aws_session_token=sts_response["Credentials"]["SessionToken"],
|
||||
region_name=aws_region_name,
|
||||
)
|
||||
|
||||
return session.get_credentials()
|
||||
elif aws_role_name is not None and aws_session_name is not None:
|
||||
sts_client = boto3.client(
|
||||
"sts",
|
||||
aws_access_key_id=aws_access_key_id, # [OPTIONAL]
|
||||
aws_secret_access_key=aws_secret_access_key, # [OPTIONAL]
|
||||
)
|
||||
|
||||
sts_response = sts_client.assume_role(
|
||||
RoleArn=aws_role_name, RoleSessionName=aws_session_name
|
||||
)
|
||||
|
||||
# Extract the credentials from the response and convert to Session Credentials
|
||||
sts_credentials = sts_response["Credentials"]
|
||||
from botocore.credentials import Credentials
|
||||
|
||||
credentials = Credentials(
|
||||
access_key=sts_credentials["AccessKeyId"],
|
||||
secret_key=sts_credentials["SecretAccessKey"],
|
||||
token=sts_credentials["SessionToken"],
|
||||
)
|
||||
return credentials
|
||||
elif aws_profile_name is not None: ### CHECK SESSION ###
|
||||
# uses auth values from AWS profile usually stored in ~/.aws/credentials
|
||||
client = boto3.Session(profile_name=aws_profile_name)
|
||||
|
||||
return client.get_credentials()
|
||||
else:
|
||||
session = boto3.Session(
|
||||
aws_access_key_id=aws_access_key_id,
|
||||
aws_secret_access_key=aws_secret_access_key,
|
||||
region_name=aws_region_name,
|
||||
)
|
||||
|
||||
return session.get_credentials()
|
||||
|
||||
async def async_streaming(
|
||||
self,
|
||||
model: str,
|
||||
messages: list,
|
||||
api_base: str,
|
||||
model_response: ModelResponse,
|
||||
print_verbose: Callable,
|
||||
data: str,
|
||||
timeout: Optional[Union[float, httpx.Timeout]],
|
||||
encoding,
|
||||
logging_obj,
|
||||
stream,
|
||||
optional_params: dict,
|
||||
litellm_params=None,
|
||||
logger_fn=None,
|
||||
headers={},
|
||||
client: Optional[AsyncHTTPHandler] = None,
|
||||
) -> CustomStreamWrapper:
|
||||
streaming_response = CustomStreamWrapper(
|
||||
completion_stream=None,
|
||||
make_call=partial(
|
||||
make_call,
|
||||
client=client,
|
||||
api_base=api_base,
|
||||
headers=headers,
|
||||
data=data,
|
||||
model=model,
|
||||
messages=messages,
|
||||
logging_obj=logging_obj,
|
||||
),
|
||||
model=model,
|
||||
custom_llm_provider="bedrock",
|
||||
logging_obj=logging_obj,
|
||||
)
|
||||
return streaming_response
|
||||
|
||||
async def async_completion(
|
||||
self,
|
||||
model: str,
|
||||
messages: list,
|
||||
api_base: str,
|
||||
model_response: ModelResponse,
|
||||
print_verbose: Callable,
|
||||
data: str,
|
||||
timeout: Optional[Union[float, httpx.Timeout]],
|
||||
encoding,
|
||||
logging_obj,
|
||||
stream,
|
||||
optional_params: dict,
|
||||
litellm_params=None,
|
||||
logger_fn=None,
|
||||
headers={},
|
||||
client: Optional[AsyncHTTPHandler] = None,
|
||||
) -> Union[ModelResponse, CustomStreamWrapper]:
|
||||
if client is None:
|
||||
_params = {}
|
||||
if timeout is not None:
|
||||
if isinstance(timeout, float) or isinstance(timeout, int):
|
||||
timeout = httpx.Timeout(timeout)
|
||||
_params["timeout"] = timeout
|
||||
client = AsyncHTTPHandler(**_params) # type: ignore
|
||||
else:
|
||||
client = client # type: ignore
|
||||
|
||||
try:
|
||||
response = await client.post(api_base, headers=headers, data=data) # type: ignore
|
||||
response.raise_for_status()
|
||||
except httpx.HTTPStatusError as err:
|
||||
error_code = err.response.status_code
|
||||
raise BedrockError(status_code=error_code, message=err.response.text)
|
||||
except httpx.TimeoutException as e:
|
||||
raise BedrockError(status_code=408, message="Timeout error occurred.")
|
||||
|
||||
return self.process_response(
|
||||
model=model,
|
||||
response=response,
|
||||
model_response=model_response,
|
||||
stream=stream if isinstance(stream, bool) else False,
|
||||
logging_obj=logging_obj,
|
||||
api_key="",
|
||||
data=data,
|
||||
messages=messages,
|
||||
print_verbose=print_verbose,
|
||||
optional_params=optional_params,
|
||||
encoding=encoding,
|
||||
)
|
||||
|
||||
def completion(
|
||||
self,
|
||||
model: str,
|
||||
messages: list,
|
||||
custom_prompt_dict: dict,
|
||||
model_response: ModelResponse,
|
||||
print_verbose: Callable,
|
||||
encoding,
|
||||
logging_obj,
|
||||
optional_params: dict,
|
||||
acompletion: bool,
|
||||
timeout: Optional[Union[float, httpx.Timeout]],
|
||||
litellm_params=None,
|
||||
logger_fn=None,
|
||||
extra_headers: Optional[dict] = None,
|
||||
client: Optional[Union[AsyncHTTPHandler, HTTPHandler]] = None,
|
||||
):
|
||||
try:
|
||||
import boto3
|
||||
|
||||
from botocore.auth import SigV4Auth
|
||||
from botocore.awsrequest import AWSRequest
|
||||
from botocore.credentials import Credentials
|
||||
except ImportError:
|
||||
raise ImportError("Missing boto3 to call bedrock. Run 'pip install boto3'.")
|
||||
|
||||
## SETUP ##
|
||||
stream = optional_params.pop("stream", None)
|
||||
modelId = optional_params.pop("model_id", None)
|
||||
if modelId is not None:
|
||||
modelId = self.encode_model_id(model_id=modelId)
|
||||
else:
|
||||
modelId = model
|
||||
|
||||
provider = model.split(".")[0]
|
||||
|
||||
## CREDENTIALS ##
|
||||
# pop aws_secret_access_key, aws_access_key_id, aws_region_name from kwargs, since completion calls fail with them
|
||||
aws_secret_access_key = optional_params.pop("aws_secret_access_key", None)
|
||||
aws_access_key_id = optional_params.pop("aws_access_key_id", None)
|
||||
aws_region_name = optional_params.pop("aws_region_name", None)
|
||||
aws_role_name = optional_params.pop("aws_role_name", None)
|
||||
aws_session_name = optional_params.pop("aws_session_name", None)
|
||||
aws_profile_name = optional_params.pop("aws_profile_name", None)
|
||||
aws_bedrock_runtime_endpoint = optional_params.pop(
|
||||
"aws_bedrock_runtime_endpoint", None
|
||||
) # https://bedrock-runtime.{region_name}.amazonaws.com
|
||||
aws_web_identity_token = optional_params.pop("aws_web_identity_token", None)
|
||||
|
||||
### SET REGION NAME ###
|
||||
if aws_region_name is None:
|
||||
# check env #
|
||||
litellm_aws_region_name = get_secret("AWS_REGION_NAME", None)
|
||||
|
||||
if litellm_aws_region_name is not None and isinstance(
|
||||
litellm_aws_region_name, str
|
||||
):
|
||||
aws_region_name = litellm_aws_region_name
|
||||
|
||||
standard_aws_region_name = get_secret("AWS_REGION", None)
|
||||
if standard_aws_region_name is not None and isinstance(
|
||||
standard_aws_region_name, str
|
||||
):
|
||||
aws_region_name = standard_aws_region_name
|
||||
|
||||
if aws_region_name is None:
|
||||
aws_region_name = "us-west-2"
|
||||
|
||||
credentials: Credentials = self.get_credentials(
|
||||
aws_access_key_id=aws_access_key_id,
|
||||
aws_secret_access_key=aws_secret_access_key,
|
||||
aws_region_name=aws_region_name,
|
||||
aws_session_name=aws_session_name,
|
||||
aws_profile_name=aws_profile_name,
|
||||
aws_role_name=aws_role_name,
|
||||
aws_web_identity_token=aws_web_identity_token,
|
||||
)
|
||||
|
||||
### SET RUNTIME ENDPOINT ###
|
||||
endpoint_url = ""
|
||||
env_aws_bedrock_runtime_endpoint = get_secret("AWS_BEDROCK_RUNTIME_ENDPOINT")
|
||||
if aws_bedrock_runtime_endpoint is not None and isinstance(
|
||||
aws_bedrock_runtime_endpoint, str
|
||||
):
|
||||
endpoint_url = aws_bedrock_runtime_endpoint
|
||||
elif env_aws_bedrock_runtime_endpoint and isinstance(
|
||||
env_aws_bedrock_runtime_endpoint, str
|
||||
):
|
||||
endpoint_url = env_aws_bedrock_runtime_endpoint
|
||||
else:
|
||||
endpoint_url = f"https://bedrock-runtime.{aws_region_name}.amazonaws.com"
|
||||
|
||||
if (stream is not None and stream is True) and provider != "ai21":
|
||||
endpoint_url = f"{endpoint_url}/model/{modelId}/converse-stream"
|
||||
else:
|
||||
endpoint_url = f"{endpoint_url}/model/{modelId}/converse"
|
||||
|
||||
sigv4 = SigV4Auth(credentials, "bedrock", aws_region_name)
|
||||
|
||||
# Separate system prompt from rest of message
|
||||
system_prompt_indices = []
|
||||
system_content_blocks: List[SystemContentBlock] = []
|
||||
for idx, message in enumerate(messages):
|
||||
if message["role"] == "system":
|
||||
_system_content_block = SystemContentBlock(text=message["content"])
|
||||
system_content_blocks.append(_system_content_block)
|
||||
system_prompt_indices.append(idx)
|
||||
if len(system_prompt_indices) > 0:
|
||||
for idx in reversed(system_prompt_indices):
|
||||
messages.pop(idx)
|
||||
|
||||
inference_params = copy.deepcopy(optional_params)
|
||||
additional_request_keys = []
|
||||
additional_request_params = {}
|
||||
supported_converse_params = AmazonConverseConfig.__annotations__.keys()
|
||||
supported_tool_call_params = ["tools", "tool_choice"]
|
||||
## TRANSFORMATION ##
|
||||
# send all model-specific params in 'additional_request_params'
|
||||
for k, v in inference_params.items():
|
||||
if (
|
||||
k not in supported_converse_params
|
||||
and k not in supported_tool_call_params
|
||||
):
|
||||
additional_request_params[k] = v
|
||||
additional_request_keys.append(k)
|
||||
for key in additional_request_keys:
|
||||
inference_params.pop(key, None)
|
||||
|
||||
bedrock_messages: List[MessageBlock] = _bedrock_converse_messages_pt(
|
||||
messages=messages
|
||||
)
|
||||
bedrock_tools: List[ToolBlock] = _bedrock_tools_pt(
|
||||
inference_params.pop("tools", [])
|
||||
)
|
||||
bedrock_tool_config: Optional[ToolConfigBlock] = None
|
||||
if len(bedrock_tools) > 0:
|
||||
tool_choice_values: ToolChoiceValuesBlock = inference_params.pop(
|
||||
"tool_choice", None
|
||||
)
|
||||
bedrock_tool_config = ToolConfigBlock(
|
||||
tools=bedrock_tools,
|
||||
)
|
||||
if tool_choice_values is not None:
|
||||
bedrock_tool_config["toolChoice"] = tool_choice_values
|
||||
|
||||
_data: RequestObject = {
|
||||
"messages": bedrock_messages,
|
||||
"additionalModelRequestFields": additional_request_params,
|
||||
"system": system_content_blocks,
|
||||
"inferenceConfig": InferenceConfig(**inference_params),
|
||||
}
|
||||
if bedrock_tool_config is not None:
|
||||
_data["toolConfig"] = bedrock_tool_config
|
||||
data = json.dumps(_data)
|
||||
## COMPLETION CALL
|
||||
|
||||
headers = {"Content-Type": "application/json"}
|
||||
if extra_headers is not None:
|
||||
headers = {"Content-Type": "application/json", **extra_headers}
|
||||
request = AWSRequest(
|
||||
method="POST", url=endpoint_url, data=data, headers=headers
|
||||
)
|
||||
sigv4.add_auth(request)
|
||||
prepped = request.prepare()
|
||||
|
||||
## LOGGING
|
||||
logging_obj.pre_call(
|
||||
input=messages,
|
||||
api_key="",
|
||||
additional_args={
|
||||
"complete_input_dict": data,
|
||||
"api_base": prepped.url,
|
||||
"headers": prepped.headers,
|
||||
},
|
||||
)
|
||||
|
||||
### ROUTING (ASYNC, STREAMING, SYNC)
|
||||
if acompletion:
|
||||
if isinstance(client, HTTPHandler):
|
||||
client = None
|
||||
if stream is True and provider != "ai21":
|
||||
return self.async_streaming(
|
||||
model=model,
|
||||
messages=messages,
|
||||
data=data,
|
||||
api_base=prepped.url,
|
||||
model_response=model_response,
|
||||
print_verbose=print_verbose,
|
||||
encoding=encoding,
|
||||
logging_obj=logging_obj,
|
||||
optional_params=optional_params,
|
||||
stream=True,
|
||||
litellm_params=litellm_params,
|
||||
logger_fn=logger_fn,
|
||||
headers=prepped.headers,
|
||||
timeout=timeout,
|
||||
client=client,
|
||||
) # type: ignore
|
||||
### ASYNC COMPLETION
|
||||
return self.async_completion(
|
||||
model=model,
|
||||
messages=messages,
|
||||
data=data,
|
||||
api_base=prepped.url,
|
||||
model_response=model_response,
|
||||
print_verbose=print_verbose,
|
||||
encoding=encoding,
|
||||
logging_obj=logging_obj,
|
||||
optional_params=optional_params,
|
||||
stream=stream, # type: ignore
|
||||
litellm_params=litellm_params,
|
||||
logger_fn=logger_fn,
|
||||
headers=prepped.headers,
|
||||
timeout=timeout,
|
||||
client=client,
|
||||
) # type: ignore
|
||||
|
||||
if (stream is not None and stream is True) and provider != "ai21":
|
||||
|
||||
streaming_response = CustomStreamWrapper(
|
||||
completion_stream=None,
|
||||
make_call=partial(
|
||||
make_sync_call,
|
||||
client=None,
|
||||
api_base=prepped.url,
|
||||
headers=prepped.headers, # type: ignore
|
||||
data=data,
|
||||
model=model,
|
||||
messages=messages,
|
||||
logging_obj=logging_obj,
|
||||
),
|
||||
model=model,
|
||||
custom_llm_provider="bedrock",
|
||||
logging_obj=logging_obj,
|
||||
)
|
||||
|
||||
return streaming_response
|
||||
### COMPLETION
|
||||
|
||||
if client is None or isinstance(client, AsyncHTTPHandler):
|
||||
_params = {}
|
||||
if timeout is not None:
|
||||
if isinstance(timeout, float) or isinstance(timeout, int):
|
||||
timeout = httpx.Timeout(timeout)
|
||||
_params["timeout"] = timeout
|
||||
client = HTTPHandler(**_params) # type: ignore
|
||||
else:
|
||||
client = client
|
||||
try:
|
||||
response = client.post(url=prepped.url, headers=prepped.headers, data=data) # type: ignore
|
||||
response.raise_for_status()
|
||||
except httpx.HTTPStatusError as err:
|
||||
error_code = err.response.status_code
|
||||
raise BedrockError(status_code=error_code, message=response.text)
|
||||
except httpx.TimeoutException:
|
||||
raise BedrockError(status_code=408, message="Timeout error occurred.")
|
||||
|
||||
return self.process_response(
|
||||
model=model,
|
||||
response=response,
|
||||
model_response=model_response,
|
||||
stream=stream,
|
||||
logging_obj=logging_obj,
|
||||
optional_params=optional_params,
|
||||
api_key="",
|
||||
data=data,
|
||||
messages=messages,
|
||||
print_verbose=print_verbose,
|
||||
encoding=encoding,
|
||||
)
|
||||
|
||||
|
||||
def get_response_stream_shape():
|
||||
from botocore.model import ServiceModel
|
||||
from botocore.loaders import Loader
|
||||
|
|
@ -1084,6 +1859,61 @@ class AWSEventStreamDecoder:
|
|||
self.model = model
|
||||
self.parser = EventStreamJSONParser()
|
||||
|
||||
def converse_chunk_parser(self, chunk_data: dict) -> GenericStreamingChunk:
|
||||
try:
|
||||
text = ""
|
||||
tool_use: Optional[ChatCompletionToolCallChunk] = None
|
||||
is_finished = False
|
||||
finish_reason = ""
|
||||
usage: Optional[ConverseTokenUsageBlock] = None
|
||||
|
||||
index = int(chunk_data.get("contentBlockIndex", 0))
|
||||
if "start" in chunk_data:
|
||||
start_obj = ContentBlockStartEvent(**chunk_data["start"])
|
||||
if (
|
||||
start_obj is not None
|
||||
and "toolUse" in start_obj
|
||||
and start_obj["toolUse"] is not None
|
||||
):
|
||||
tool_use = {
|
||||
"id": start_obj["toolUse"]["toolUseId"],
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": start_obj["toolUse"]["name"],
|
||||
"arguments": "",
|
||||
},
|
||||
}
|
||||
elif "delta" in chunk_data:
|
||||
delta_obj = ContentBlockDeltaEvent(**chunk_data["delta"])
|
||||
if "text" in delta_obj:
|
||||
text = delta_obj["text"]
|
||||
elif "toolUse" in delta_obj:
|
||||
tool_use = {
|
||||
"id": None,
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": None,
|
||||
"arguments": delta_obj["toolUse"]["input"],
|
||||
},
|
||||
}
|
||||
elif "stopReason" in chunk_data:
|
||||
finish_reason = map_finish_reason(chunk_data.get("stopReason", "stop"))
|
||||
is_finished = True
|
||||
elif "usage" in chunk_data:
|
||||
usage = ConverseTokenUsageBlock(**chunk_data["usage"]) # type: ignore
|
||||
|
||||
response = GenericStreamingChunk(
|
||||
text=text,
|
||||
tool_use=tool_use,
|
||||
is_finished=is_finished,
|
||||
finish_reason=finish_reason,
|
||||
usage=usage,
|
||||
index=index,
|
||||
)
|
||||
return response
|
||||
except Exception as e:
|
||||
raise Exception("Received streaming error - {}".format(str(e)))
|
||||
|
||||
def _chunk_parser(self, chunk_data: dict) -> GenericStreamingChunk:
|
||||
text = ""
|
||||
is_finished = False
|
||||
|
|
@ -1091,24 +1921,17 @@ class AWSEventStreamDecoder:
|
|||
if "outputText" in chunk_data:
|
||||
text = chunk_data["outputText"]
|
||||
# ai21 mapping
|
||||
if "ai21" in self.model: # fake ai21 streaming
|
||||
elif "ai21" in self.model: # fake ai21 streaming
|
||||
text = chunk_data.get("completions")[0].get("data").get("text") # type: ignore
|
||||
is_finished = True
|
||||
finish_reason = "stop"
|
||||
######## bedrock.anthropic mappings ###############
|
||||
elif "completion" in chunk_data: # not claude-3
|
||||
text = chunk_data["completion"] # bedrock.anthropic
|
||||
stop_reason = chunk_data.get("stop_reason", None)
|
||||
if stop_reason != None:
|
||||
is_finished = True
|
||||
finish_reason = stop_reason
|
||||
elif "delta" in chunk_data:
|
||||
if chunk_data["delta"].get("text", None) is not None:
|
||||
text = chunk_data["delta"]["text"]
|
||||
stop_reason = chunk_data["delta"].get("stop_reason", None)
|
||||
if stop_reason != None:
|
||||
is_finished = True
|
||||
finish_reason = stop_reason
|
||||
elif (
|
||||
"contentBlockIndex" in chunk_data
|
||||
or "stopReason" in chunk_data
|
||||
or "metrics" in chunk_data
|
||||
):
|
||||
return self.converse_chunk_parser(chunk_data=chunk_data)
|
||||
######## bedrock.mistral mappings ###############
|
||||
elif "outputs" in chunk_data:
|
||||
if (
|
||||
|
|
@ -1117,7 +1940,7 @@ class AWSEventStreamDecoder:
|
|||
):
|
||||
text = chunk_data["outputs"][0]["text"]
|
||||
stop_reason = chunk_data.get("stop_reason", None)
|
||||
if stop_reason != None:
|
||||
if stop_reason is not None:
|
||||
is_finished = True
|
||||
finish_reason = stop_reason
|
||||
######## bedrock.cohere mappings ###############
|
||||
|
|
@ -1135,11 +1958,12 @@ class AWSEventStreamDecoder:
|
|||
is_finished = True
|
||||
finish_reason = chunk_data["completionReason"]
|
||||
return GenericStreamingChunk(
|
||||
**{
|
||||
"text": text,
|
||||
"is_finished": is_finished,
|
||||
"finish_reason": finish_reason,
|
||||
}
|
||||
text=text,
|
||||
is_finished=is_finished,
|
||||
finish_reason=finish_reason,
|
||||
usage=None,
|
||||
index=0,
|
||||
tool_use=None,
|
||||
)
|
||||
|
||||
def iter_bytes(self, iterator: Iterator[bytes]) -> Iterator[GenericStreamingChunk]:
|
||||
|
|
@ -1176,9 +2000,14 @@ class AWSEventStreamDecoder:
|
|||
parsed_response = self.parser.parse(response_dict, get_response_stream_shape())
|
||||
if response_dict["status_code"] != 200:
|
||||
raise ValueError(f"Bad response code, expected 200: {response_dict}")
|
||||
if "chunk" in parsed_response:
|
||||
chunk = parsed_response.get("chunk")
|
||||
if not chunk:
|
||||
return None
|
||||
return chunk.get("bytes").decode() # type: ignore[no-any-return]
|
||||
else:
|
||||
chunk = response_dict.get("body")
|
||||
if not chunk:
|
||||
return None
|
||||
|
||||
chunk = parsed_response.get("chunk")
|
||||
if not chunk:
|
||||
return None
|
||||
|
||||
return chunk.get("bytes").decode() # type: ignore[no-any-return]
|
||||
return chunk.decode() # type: ignore[no-any-return]
|
||||
|
|
|
|||
|
|
@ -1,4 +1,5 @@
|
|||
import httpx, asyncio, traceback
|
||||
import litellm
|
||||
import httpx, asyncio, traceback, os
|
||||
from typing import Optional, Union, Mapping, Any
|
||||
|
||||
# https://www.python-httpx.org/advanced/timeouts
|
||||
|
|
@ -11,6 +12,30 @@ class AsyncHTTPHandler:
|
|||
timeout: Optional[Union[float, httpx.Timeout]] = None,
|
||||
concurrent_limit=1000,
|
||||
):
|
||||
async_proxy_mounts = None
|
||||
# Check if the HTTP_PROXY and HTTPS_PROXY environment variables are set and use them accordingly.
|
||||
http_proxy = os.getenv("HTTP_PROXY", None)
|
||||
https_proxy = os.getenv("HTTPS_PROXY", None)
|
||||
no_proxy = os.getenv("NO_PROXY", None)
|
||||
ssl_verify = bool(os.getenv("SSL_VERIFY", litellm.ssl_verify))
|
||||
cert = os.getenv(
|
||||
"SSL_CERTIFICATE", litellm.ssl_certificate
|
||||
) # /path/to/client.pem
|
||||
|
||||
if http_proxy is not None and https_proxy is not None:
|
||||
async_proxy_mounts = {
|
||||
"http://": httpx.AsyncHTTPTransport(proxy=httpx.Proxy(url=http_proxy)),
|
||||
"https://": httpx.AsyncHTTPTransport(
|
||||
proxy=httpx.Proxy(url=https_proxy)
|
||||
),
|
||||
}
|
||||
# assume no_proxy is a list of comma separated urls
|
||||
if no_proxy is not None and isinstance(no_proxy, str):
|
||||
no_proxy_urls = no_proxy.split(",")
|
||||
|
||||
for url in no_proxy_urls: # set no-proxy support for specific urls
|
||||
async_proxy_mounts[url] = None # type: ignore
|
||||
|
||||
if timeout is None:
|
||||
timeout = _DEFAULT_TIMEOUT
|
||||
# Create a client with a connection pool
|
||||
|
|
@ -20,6 +45,9 @@ class AsyncHTTPHandler:
|
|||
max_connections=concurrent_limit,
|
||||
max_keepalive_connections=concurrent_limit,
|
||||
),
|
||||
verify=ssl_verify,
|
||||
mounts=async_proxy_mounts,
|
||||
cert=cert,
|
||||
)
|
||||
|
||||
async def close(self):
|
||||
|
|
@ -56,9 +84,9 @@ class AsyncHTTPHandler:
|
|||
response.raise_for_status()
|
||||
return response
|
||||
except httpx.HTTPStatusError as e:
|
||||
raise
|
||||
raise e
|
||||
except Exception as e:
|
||||
raise
|
||||
raise e
|
||||
|
||||
def __del__(self) -> None:
|
||||
try:
|
||||
|
|
@ -77,6 +105,28 @@ class HTTPHandler:
|
|||
if timeout is None:
|
||||
timeout = _DEFAULT_TIMEOUT
|
||||
|
||||
# Check if the HTTP_PROXY and HTTPS_PROXY environment variables are set and use them accordingly.
|
||||
http_proxy = os.getenv("HTTP_PROXY", None)
|
||||
https_proxy = os.getenv("HTTPS_PROXY", None)
|
||||
no_proxy = os.getenv("NO_PROXY", None)
|
||||
ssl_verify = bool(os.getenv("SSL_VERIFY", litellm.ssl_verify))
|
||||
cert = os.getenv(
|
||||
"SSL_CERTIFICATE", litellm.ssl_certificate
|
||||
) # /path/to/client.pem
|
||||
|
||||
sync_proxy_mounts = None
|
||||
if http_proxy is not None and https_proxy is not None:
|
||||
sync_proxy_mounts = {
|
||||
"http://": httpx.HTTPTransport(proxy=httpx.Proxy(url=http_proxy)),
|
||||
"https://": httpx.HTTPTransport(proxy=httpx.Proxy(url=https_proxy)),
|
||||
}
|
||||
# assume no_proxy is a list of comma separated urls
|
||||
if no_proxy is not None and isinstance(no_proxy, str):
|
||||
no_proxy_urls = no_proxy.split(",")
|
||||
|
||||
for url in no_proxy_urls: # set no-proxy support for specific urls
|
||||
sync_proxy_mounts[url] = None # type: ignore
|
||||
|
||||
if client is None:
|
||||
# Create a client with a connection pool
|
||||
self.client = httpx.Client(
|
||||
|
|
@ -85,6 +135,9 @@ class HTTPHandler:
|
|||
max_connections=concurrent_limit,
|
||||
max_keepalive_connections=concurrent_limit,
|
||||
),
|
||||
verify=ssl_verify,
|
||||
mounts=sync_proxy_mounts,
|
||||
cert=cert,
|
||||
)
|
||||
else:
|
||||
self.client = client
|
||||
|
|
@ -103,12 +156,13 @@ class HTTPHandler:
|
|||
self,
|
||||
url: str,
|
||||
data: Optional[Union[dict, str]] = None,
|
||||
json: Optional[Union[dict, str]] = None,
|
||||
params: Optional[dict] = None,
|
||||
headers: Optional[dict] = None,
|
||||
stream: bool = False,
|
||||
):
|
||||
req = self.client.build_request(
|
||||
"POST", url, data=data, params=params, headers=headers # type: ignore
|
||||
"POST", url, data=data, json=json, params=params, headers=headers # type: ignore
|
||||
)
|
||||
response = self.client.send(req, stream=stream)
|
||||
return response
|
||||
|
|
|
|||
|
|
@ -1,13 +1,14 @@
|
|||
import os, types, traceback, copy, asyncio
|
||||
import json
|
||||
from enum import Enum
|
||||
import types
|
||||
import traceback
|
||||
import copy
|
||||
import time
|
||||
from typing import Callable, Optional
|
||||
from litellm.utils import ModelResponse, get_secret, Choices, Message, Usage
|
||||
from litellm.utils import ModelResponse, Choices, Message, Usage
|
||||
import litellm
|
||||
import sys, httpx
|
||||
import httpx
|
||||
from .prompt_templates.factory import prompt_factory, custom_prompt, get_system_prompt
|
||||
from packaging.version import Version
|
||||
from litellm import verbose_logger
|
||||
|
||||
|
||||
class GeminiError(Exception):
|
||||
|
|
@ -264,7 +265,8 @@ def completion(
|
|||
choices_list.append(choice_obj)
|
||||
model_response["choices"] = choices_list
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.error("LiteLLM.gemini.py: Exception occured - {}".format(str(e)))
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
raise GeminiError(
|
||||
message=traceback.format_exc(), status_code=response.status_code
|
||||
)
|
||||
|
|
@ -356,7 +358,8 @@ async def async_completion(
|
|||
choices_list.append(choice_obj)
|
||||
model_response["choices"] = choices_list
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.error("LiteLLM.gemini.py: Exception occured - {}".format(str(e)))
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
raise GeminiError(
|
||||
message=traceback.format_exc(), status_code=response.status_code
|
||||
)
|
||||
|
|
|
|||
|
|
@ -2,10 +2,12 @@ from itertools import chain
|
|||
import requests, types, time # type: ignore
|
||||
import json, uuid
|
||||
import traceback
|
||||
from typing import Optional
|
||||
from typing import Optional, List
|
||||
import litellm
|
||||
from litellm.types.utils import ProviderField
|
||||
import httpx, aiohttp, asyncio # type: ignore
|
||||
from .prompt_templates.factory import prompt_factory, custom_prompt
|
||||
from litellm import verbose_logger
|
||||
|
||||
|
||||
class OllamaError(Exception):
|
||||
|
|
@ -124,6 +126,19 @@ class OllamaConfig:
|
|||
)
|
||||
and v is not None
|
||||
}
|
||||
|
||||
def get_required_params(self) -> List[ProviderField]:
|
||||
"""For a given provider, return it's required fields with a description"""
|
||||
return [
|
||||
ProviderField(
|
||||
field_name="base_url",
|
||||
field_type="string",
|
||||
field_description="Your Ollama API Base",
|
||||
field_value="http://10.10.11.249:11434",
|
||||
)
|
||||
]
|
||||
|
||||
|
||||
def get_supported_openai_params(
|
||||
self,
|
||||
):
|
||||
|
|
@ -138,10 +153,12 @@ class OllamaConfig:
|
|||
"response_format",
|
||||
]
|
||||
|
||||
|
||||
# ollama wants plain base64 jpeg/png files as images. strip any leading dataURI
|
||||
# and convert to jpeg if necessary.
|
||||
def _convert_image(image):
|
||||
import base64, io
|
||||
|
||||
try:
|
||||
from PIL import Image
|
||||
except:
|
||||
|
|
@ -391,7 +408,13 @@ async def ollama_async_streaming(url, data, model_response, encoding, logging_ob
|
|||
async for transformed_chunk in streamwrapper:
|
||||
yield transformed_chunk
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(
|
||||
"LiteLLM.ollama.py::ollama_async_streaming(): Exception occured - {}".format(
|
||||
str(e)
|
||||
)
|
||||
)
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
|
||||
raise e
|
||||
|
||||
|
||||
|
|
@ -455,7 +478,12 @@ async def ollama_acompletion(url, data, model_response, encoding, logging_obj):
|
|||
)
|
||||
return model_response
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(
|
||||
"LiteLLM.ollama.py::ollama_acompletion(): Exception occured - {}".format(
|
||||
str(e)
|
||||
)
|
||||
)
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
raise e
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -1,11 +1,15 @@
|
|||
from itertools import chain
|
||||
import requests, types, time
|
||||
import json, uuid
|
||||
import requests
|
||||
import types
|
||||
import time
|
||||
import json
|
||||
import uuid
|
||||
import traceback
|
||||
from typing import Optional
|
||||
from litellm import verbose_logger
|
||||
import litellm
|
||||
import httpx, aiohttp, asyncio
|
||||
from .prompt_templates.factory import prompt_factory, custom_prompt
|
||||
import httpx
|
||||
import aiohttp
|
||||
|
||||
|
||||
class OllamaError(Exception):
|
||||
|
|
@ -299,7 +303,10 @@ def get_ollama_response(
|
|||
tool_calls=[
|
||||
{
|
||||
"id": f"call_{str(uuid.uuid4())}",
|
||||
"function": {"name": function_call["name"], "arguments": json.dumps(function_call["arguments"])},
|
||||
"function": {
|
||||
"name": function_call["name"],
|
||||
"arguments": json.dumps(function_call["arguments"]),
|
||||
},
|
||||
"type": "function",
|
||||
}
|
||||
],
|
||||
|
|
@ -307,7 +314,9 @@ def get_ollama_response(
|
|||
model_response["choices"][0]["message"] = message
|
||||
model_response["choices"][0]["finish_reason"] = "tool_calls"
|
||||
else:
|
||||
model_response["choices"][0]["message"]["content"] = response_json["message"]["content"]
|
||||
model_response["choices"][0]["message"]["content"] = response_json["message"][
|
||||
"content"
|
||||
]
|
||||
model_response["created"] = int(time.time())
|
||||
model_response["model"] = "ollama/" + model
|
||||
prompt_tokens = response_json.get("prompt_eval_count", litellm.token_counter(messages=messages)) # type: ignore
|
||||
|
|
@ -361,7 +370,10 @@ def ollama_completion_stream(url, api_key, data, logging_obj):
|
|||
tool_calls=[
|
||||
{
|
||||
"id": f"call_{str(uuid.uuid4())}",
|
||||
"function": {"name": function_call["name"], "arguments": json.dumps(function_call["arguments"])},
|
||||
"function": {
|
||||
"name": function_call["name"],
|
||||
"arguments": json.dumps(function_call["arguments"]),
|
||||
},
|
||||
"type": "function",
|
||||
}
|
||||
],
|
||||
|
|
@ -410,9 +422,10 @@ async def ollama_async_streaming(
|
|||
first_chunk_content = first_chunk.choices[0].delta.content or ""
|
||||
response_content = first_chunk_content + "".join(
|
||||
[
|
||||
chunk.choices[0].delta.content
|
||||
async for chunk in streamwrapper
|
||||
if chunk.choices[0].delta.content]
|
||||
chunk.choices[0].delta.content
|
||||
async for chunk in streamwrapper
|
||||
if chunk.choices[0].delta.content
|
||||
]
|
||||
)
|
||||
function_call = json.loads(response_content)
|
||||
delta = litellm.utils.Delta(
|
||||
|
|
@ -420,7 +433,10 @@ async def ollama_async_streaming(
|
|||
tool_calls=[
|
||||
{
|
||||
"id": f"call_{str(uuid.uuid4())}",
|
||||
"function": {"name": function_call["name"], "arguments": json.dumps(function_call["arguments"])},
|
||||
"function": {
|
||||
"name": function_call["name"],
|
||||
"arguments": json.dumps(function_call["arguments"]),
|
||||
},
|
||||
"type": "function",
|
||||
}
|
||||
],
|
||||
|
|
@ -433,7 +449,8 @@ async def ollama_async_streaming(
|
|||
async for transformed_chunk in streamwrapper:
|
||||
yield transformed_chunk
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.error("LiteLLM.gemini(): Exception occured - {}".format(str(e)))
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
|
||||
|
||||
async def ollama_acompletion(
|
||||
|
|
@ -483,7 +500,10 @@ async def ollama_acompletion(
|
|||
tool_calls=[
|
||||
{
|
||||
"id": f"call_{str(uuid.uuid4())}",
|
||||
"function": {"name": function_call["name"], "arguments": json.dumps(function_call["arguments"])},
|
||||
"function": {
|
||||
"name": function_call["name"],
|
||||
"arguments": json.dumps(function_call["arguments"]),
|
||||
},
|
||||
"type": "function",
|
||||
}
|
||||
],
|
||||
|
|
@ -491,7 +511,9 @@ async def ollama_acompletion(
|
|||
model_response["choices"][0]["message"] = message
|
||||
model_response["choices"][0]["finish_reason"] = "tool_calls"
|
||||
else:
|
||||
model_response["choices"][0]["message"]["content"] = response_json["message"]["content"]
|
||||
model_response["choices"][0]["message"]["content"] = response_json[
|
||||
"message"
|
||||
]["content"]
|
||||
|
||||
model_response["created"] = int(time.time())
|
||||
model_response["model"] = "ollama_chat/" + data["model"]
|
||||
|
|
@ -509,5 +531,9 @@ async def ollama_acompletion(
|
|||
)
|
||||
return model_response
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(
|
||||
"LiteLLM.ollama_acompletion(): Exception occured - {}".format(str(e))
|
||||
)
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
|
||||
raise e
|
||||
|
|
|
|||
|
|
@ -6,6 +6,7 @@ from typing import (
|
|||
Literal,
|
||||
Iterable,
|
||||
)
|
||||
import hashlib
|
||||
from typing_extensions import override, overload
|
||||
from pydantic import BaseModel
|
||||
import types, time, json, traceback
|
||||
|
|
@ -504,6 +505,64 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
def __init__(self) -> None:
|
||||
super().__init__()
|
||||
|
||||
def _get_openai_client(
|
||||
self,
|
||||
is_async: bool,
|
||||
api_key: Optional[str] = None,
|
||||
api_base: Optional[str] = None,
|
||||
timeout: Union[float, httpx.Timeout] = httpx.Timeout(None),
|
||||
max_retries: Optional[int] = None,
|
||||
organization: Optional[str] = None,
|
||||
client: Optional[Union[OpenAI, AsyncOpenAI]] = None,
|
||||
):
|
||||
args = locals()
|
||||
if client is None:
|
||||
if not isinstance(max_retries, int):
|
||||
raise OpenAIError(
|
||||
status_code=422,
|
||||
message="max retries must be an int. Passed in value: {}".format(
|
||||
max_retries
|
||||
),
|
||||
)
|
||||
# Creating a new OpenAI Client
|
||||
# check in memory cache before creating a new one
|
||||
# Convert the API key to bytes
|
||||
hashed_api_key = None
|
||||
if api_key is not None:
|
||||
hash_object = hashlib.sha256(api_key.encode())
|
||||
# Hexadecimal representation of the hash
|
||||
hashed_api_key = hash_object.hexdigest()
|
||||
|
||||
_cache_key = f"hashed_api_key={hashed_api_key},api_base={api_base},timeout={timeout},max_retries={max_retries},organization={organization},is_async={is_async}"
|
||||
|
||||
if _cache_key in litellm.in_memory_llm_clients_cache:
|
||||
return litellm.in_memory_llm_clients_cache[_cache_key]
|
||||
if is_async:
|
||||
_new_client: Union[OpenAI, AsyncOpenAI] = AsyncOpenAI(
|
||||
api_key=api_key,
|
||||
base_url=api_base,
|
||||
http_client=litellm.aclient_session,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
organization=organization,
|
||||
)
|
||||
else:
|
||||
_new_client = OpenAI(
|
||||
api_key=api_key,
|
||||
base_url=api_base,
|
||||
http_client=litellm.client_session,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
organization=organization,
|
||||
)
|
||||
|
||||
## SAVE CACHE KEY
|
||||
litellm.in_memory_llm_clients_cache[_cache_key] = _new_client
|
||||
return _new_client
|
||||
|
||||
else:
|
||||
return client
|
||||
|
||||
def completion(
|
||||
self,
|
||||
model_response: ModelResponse,
|
||||
|
|
@ -610,17 +669,16 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
raise OpenAIError(
|
||||
status_code=422, message="max retries must be an int"
|
||||
)
|
||||
if client is None:
|
||||
openai_client = OpenAI(
|
||||
api_key=api_key,
|
||||
base_url=api_base,
|
||||
http_client=litellm.client_session,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
organization=organization,
|
||||
)
|
||||
else:
|
||||
openai_client = client
|
||||
|
||||
openai_client = self._get_openai_client(
|
||||
is_async=False,
|
||||
api_key=api_key,
|
||||
api_base=api_base,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
organization=organization,
|
||||
client=client,
|
||||
)
|
||||
|
||||
## LOGGING
|
||||
logging_obj.pre_call(
|
||||
|
|
@ -700,17 +758,15 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
):
|
||||
response = None
|
||||
try:
|
||||
if client is None:
|
||||
openai_aclient = AsyncOpenAI(
|
||||
api_key=api_key,
|
||||
base_url=api_base,
|
||||
http_client=litellm.aclient_session,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
organization=organization,
|
||||
)
|
||||
else:
|
||||
openai_aclient = client
|
||||
openai_aclient = self._get_openai_client(
|
||||
is_async=True,
|
||||
api_key=api_key,
|
||||
api_base=api_base,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
organization=organization,
|
||||
client=client,
|
||||
)
|
||||
|
||||
## LOGGING
|
||||
logging_obj.pre_call(
|
||||
|
|
@ -754,17 +810,15 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
max_retries=None,
|
||||
headers=None,
|
||||
):
|
||||
if client is None:
|
||||
openai_client = OpenAI(
|
||||
api_key=api_key,
|
||||
base_url=api_base,
|
||||
http_client=litellm.client_session,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
organization=organization,
|
||||
)
|
||||
else:
|
||||
openai_client = client
|
||||
openai_client = self._get_openai_client(
|
||||
is_async=False,
|
||||
api_key=api_key,
|
||||
api_base=api_base,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
organization=organization,
|
||||
client=client,
|
||||
)
|
||||
## LOGGING
|
||||
logging_obj.pre_call(
|
||||
input=data["messages"],
|
||||
|
|
@ -801,17 +855,15 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
):
|
||||
response = None
|
||||
try:
|
||||
if client is None:
|
||||
openai_aclient = AsyncOpenAI(
|
||||
api_key=api_key,
|
||||
base_url=api_base,
|
||||
http_client=litellm.aclient_session,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
organization=organization,
|
||||
)
|
||||
else:
|
||||
openai_aclient = client
|
||||
openai_aclient = self._get_openai_client(
|
||||
is_async=True,
|
||||
api_key=api_key,
|
||||
api_base=api_base,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
organization=organization,
|
||||
client=client,
|
||||
)
|
||||
## LOGGING
|
||||
logging_obj.pre_call(
|
||||
input=data["messages"],
|
||||
|
|
@ -865,16 +917,14 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
):
|
||||
response = None
|
||||
try:
|
||||
if client is None:
|
||||
openai_aclient = AsyncOpenAI(
|
||||
api_key=api_key,
|
||||
base_url=api_base,
|
||||
http_client=litellm.aclient_session,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
)
|
||||
else:
|
||||
openai_aclient = client
|
||||
openai_aclient = self._get_openai_client(
|
||||
is_async=True,
|
||||
api_key=api_key,
|
||||
api_base=api_base,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
client=client,
|
||||
)
|
||||
response = await openai_aclient.embeddings.create(**data, timeout=timeout) # type: ignore
|
||||
stringified_response = response.model_dump()
|
||||
## LOGGING
|
||||
|
|
@ -922,19 +972,18 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
additional_args={"complete_input_dict": data, "api_base": api_base},
|
||||
)
|
||||
|
||||
if aembedding == True:
|
||||
if aembedding is True:
|
||||
response = self.aembedding(data=data, input=input, logging_obj=logging_obj, model_response=model_response, api_base=api_base, api_key=api_key, timeout=timeout, client=client, max_retries=max_retries) # type: ignore
|
||||
return response
|
||||
if client is None:
|
||||
openai_client = OpenAI(
|
||||
api_key=api_key,
|
||||
base_url=api_base,
|
||||
http_client=litellm.client_session,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
)
|
||||
else:
|
||||
openai_client = client
|
||||
|
||||
openai_client = self._get_openai_client(
|
||||
is_async=False,
|
||||
api_key=api_key,
|
||||
api_base=api_base,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
client=client,
|
||||
)
|
||||
|
||||
## COMPLETION CALL
|
||||
response = openai_client.embeddings.create(**data, timeout=timeout) # type: ignore
|
||||
|
|
@ -970,16 +1019,16 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
):
|
||||
response = None
|
||||
try:
|
||||
if client is None:
|
||||
openai_aclient = AsyncOpenAI(
|
||||
api_key=api_key,
|
||||
base_url=api_base,
|
||||
http_client=litellm.aclient_session,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
)
|
||||
else:
|
||||
openai_aclient = client
|
||||
|
||||
openai_aclient = self._get_openai_client(
|
||||
is_async=True,
|
||||
api_key=api_key,
|
||||
api_base=api_base,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
client=client,
|
||||
)
|
||||
|
||||
response = await openai_aclient.images.generate(**data, timeout=timeout) # type: ignore
|
||||
stringified_response = response.model_dump()
|
||||
## LOGGING
|
||||
|
|
@ -1024,16 +1073,14 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
response = self.aimage_generation(data=data, prompt=prompt, logging_obj=logging_obj, model_response=model_response, api_base=api_base, api_key=api_key, timeout=timeout, client=client, max_retries=max_retries) # type: ignore
|
||||
return response
|
||||
|
||||
if client is None:
|
||||
openai_client = OpenAI(
|
||||
api_key=api_key,
|
||||
base_url=api_base,
|
||||
http_client=litellm.client_session,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
)
|
||||
else:
|
||||
openai_client = client
|
||||
openai_client = self._get_openai_client(
|
||||
is_async=False,
|
||||
api_key=api_key,
|
||||
api_base=api_base,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
client=client,
|
||||
)
|
||||
|
||||
## LOGGING
|
||||
logging_obj.pre_call(
|
||||
|
|
@ -1098,7 +1145,7 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
atranscription: bool = False,
|
||||
):
|
||||
data = {"model": model, "file": audio_file, **optional_params}
|
||||
if atranscription == True:
|
||||
if atranscription is True:
|
||||
return self.async_audio_transcriptions(
|
||||
audio_file=audio_file,
|
||||
data=data,
|
||||
|
|
@ -1110,16 +1157,14 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
max_retries=max_retries,
|
||||
logging_obj=logging_obj,
|
||||
)
|
||||
if client is None:
|
||||
openai_client = OpenAI(
|
||||
api_key=api_key,
|
||||
base_url=api_base,
|
||||
http_client=litellm.client_session,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
)
|
||||
else:
|
||||
openai_client = client
|
||||
|
||||
openai_client = self._get_openai_client(
|
||||
is_async=False,
|
||||
api_key=api_key,
|
||||
api_base=api_base,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
)
|
||||
response = openai_client.audio.transcriptions.create(
|
||||
**data, timeout=timeout # type: ignore
|
||||
)
|
||||
|
|
@ -1149,16 +1194,15 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
logging_obj=None,
|
||||
):
|
||||
try:
|
||||
if client is None:
|
||||
openai_aclient = AsyncOpenAI(
|
||||
api_key=api_key,
|
||||
base_url=api_base,
|
||||
http_client=litellm.aclient_session,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
)
|
||||
else:
|
||||
openai_aclient = client
|
||||
openai_aclient = self._get_openai_client(
|
||||
is_async=True,
|
||||
api_key=api_key,
|
||||
api_base=api_base,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
client=client,
|
||||
)
|
||||
|
||||
response = await openai_aclient.audio.transcriptions.create(
|
||||
**data, timeout=timeout
|
||||
) # type: ignore
|
||||
|
|
@ -1197,7 +1241,7 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
client=None,
|
||||
) -> HttpxBinaryResponseContent:
|
||||
|
||||
if aspeech is not None and aspeech == True:
|
||||
if aspeech is not None and aspeech is True:
|
||||
return self.async_audio_speech(
|
||||
model=model,
|
||||
input=input,
|
||||
|
|
@ -1212,18 +1256,14 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
client=client,
|
||||
) # type: ignore
|
||||
|
||||
if client is None:
|
||||
openai_client = OpenAI(
|
||||
api_key=api_key,
|
||||
base_url=api_base,
|
||||
organization=organization,
|
||||
project=project,
|
||||
http_client=litellm.client_session,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
)
|
||||
else:
|
||||
openai_client = client
|
||||
openai_client = self._get_openai_client(
|
||||
is_async=False,
|
||||
api_key=api_key,
|
||||
api_base=api_base,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
client=client,
|
||||
)
|
||||
|
||||
response = openai_client.audio.speech.create(
|
||||
model=model,
|
||||
|
|
@ -1248,18 +1288,14 @@ class OpenAIChatCompletion(BaseLLM):
|
|||
client=None,
|
||||
) -> HttpxBinaryResponseContent:
|
||||
|
||||
if client is None:
|
||||
openai_client = AsyncOpenAI(
|
||||
api_key=api_key,
|
||||
base_url=api_base,
|
||||
organization=organization,
|
||||
project=project,
|
||||
http_client=litellm.aclient_session,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
)
|
||||
else:
|
||||
openai_client = client
|
||||
openai_client = self._get_openai_client(
|
||||
is_async=True,
|
||||
api_key=api_key,
|
||||
api_base=api_base,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
client=client,
|
||||
)
|
||||
|
||||
response = await openai_client.audio.speech.create(
|
||||
model=model,
|
||||
|
|
@ -2052,7 +2088,7 @@ class OpenAIAssistantsAPI(BaseLLM):
|
|||
async def a_add_message(
|
||||
self,
|
||||
thread_id: str,
|
||||
message_data: MessageData,
|
||||
message_data: dict,
|
||||
api_key: Optional[str],
|
||||
api_base: Optional[str],
|
||||
timeout: Union[float, httpx.Timeout],
|
||||
|
|
@ -2087,7 +2123,7 @@ class OpenAIAssistantsAPI(BaseLLM):
|
|||
def add_message(
|
||||
self,
|
||||
thread_id: str,
|
||||
message_data: MessageData,
|
||||
message_data: dict,
|
||||
api_key: Optional[str],
|
||||
api_base: Optional[str],
|
||||
timeout: Union[float, httpx.Timeout],
|
||||
|
|
@ -2102,7 +2138,7 @@ class OpenAIAssistantsAPI(BaseLLM):
|
|||
def add_message(
|
||||
self,
|
||||
thread_id: str,
|
||||
message_data: MessageData,
|
||||
message_data: dict,
|
||||
api_key: Optional[str],
|
||||
api_base: Optional[str],
|
||||
timeout: Union[float, httpx.Timeout],
|
||||
|
|
@ -2118,7 +2154,7 @@ class OpenAIAssistantsAPI(BaseLLM):
|
|||
def add_message(
|
||||
self,
|
||||
thread_id: str,
|
||||
message_data: MessageData,
|
||||
message_data: dict,
|
||||
api_key: Optional[str],
|
||||
api_base: Optional[str],
|
||||
timeout: Union[float, httpx.Timeout],
|
||||
|
|
@ -2498,6 +2534,56 @@ class OpenAIAssistantsAPI(BaseLLM):
|
|||
|
||||
return response
|
||||
|
||||
def async_run_thread_stream(
|
||||
self,
|
||||
client: AsyncOpenAI,
|
||||
thread_id: str,
|
||||
assistant_id: str,
|
||||
additional_instructions: Optional[str],
|
||||
instructions: Optional[str],
|
||||
metadata: Optional[object],
|
||||
model: Optional[str],
|
||||
tools: Optional[Iterable[AssistantToolParam]],
|
||||
event_handler: Optional[AssistantEventHandler],
|
||||
) -> AsyncAssistantStreamManager[AsyncAssistantEventHandler]:
|
||||
data = {
|
||||
"thread_id": thread_id,
|
||||
"assistant_id": assistant_id,
|
||||
"additional_instructions": additional_instructions,
|
||||
"instructions": instructions,
|
||||
"metadata": metadata,
|
||||
"model": model,
|
||||
"tools": tools,
|
||||
}
|
||||
if event_handler is not None:
|
||||
data["event_handler"] = event_handler
|
||||
return client.beta.threads.runs.stream(**data) # type: ignore
|
||||
|
||||
def run_thread_stream(
|
||||
self,
|
||||
client: OpenAI,
|
||||
thread_id: str,
|
||||
assistant_id: str,
|
||||
additional_instructions: Optional[str],
|
||||
instructions: Optional[str],
|
||||
metadata: Optional[object],
|
||||
model: Optional[str],
|
||||
tools: Optional[Iterable[AssistantToolParam]],
|
||||
event_handler: Optional[AssistantEventHandler],
|
||||
) -> AssistantStreamManager[AssistantEventHandler]:
|
||||
data = {
|
||||
"thread_id": thread_id,
|
||||
"assistant_id": assistant_id,
|
||||
"additional_instructions": additional_instructions,
|
||||
"instructions": instructions,
|
||||
"metadata": metadata,
|
||||
"model": model,
|
||||
"tools": tools,
|
||||
}
|
||||
if event_handler is not None:
|
||||
data["event_handler"] = event_handler
|
||||
return client.beta.threads.runs.stream(**data) # type: ignore
|
||||
|
||||
# fmt: off
|
||||
|
||||
@overload
|
||||
|
|
@ -2516,8 +2602,9 @@ class OpenAIAssistantsAPI(BaseLLM):
|
|||
timeout: Union[float, httpx.Timeout],
|
||||
max_retries: Optional[int],
|
||||
organization: Optional[str],
|
||||
client: Optional[AsyncOpenAI],
|
||||
client,
|
||||
arun_thread: Literal[True],
|
||||
event_handler: Optional[AssistantEventHandler],
|
||||
) -> Coroutine[None, None, Run]:
|
||||
...
|
||||
|
||||
|
|
@ -2537,8 +2624,9 @@ class OpenAIAssistantsAPI(BaseLLM):
|
|||
timeout: Union[float, httpx.Timeout],
|
||||
max_retries: Optional[int],
|
||||
organization: Optional[str],
|
||||
client: Optional[OpenAI],
|
||||
client,
|
||||
arun_thread: Optional[Literal[False]],
|
||||
event_handler: Optional[AssistantEventHandler],
|
||||
) -> Run:
|
||||
...
|
||||
|
||||
|
|
@ -2561,8 +2649,29 @@ class OpenAIAssistantsAPI(BaseLLM):
|
|||
organization: Optional[str],
|
||||
client=None,
|
||||
arun_thread=None,
|
||||
event_handler: Optional[AssistantEventHandler] = None,
|
||||
):
|
||||
if arun_thread is not None and arun_thread == True:
|
||||
if stream is not None and stream == True:
|
||||
_client = self.async_get_openai_client(
|
||||
api_key=api_key,
|
||||
api_base=api_base,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
organization=organization,
|
||||
client=client,
|
||||
)
|
||||
return self.async_run_thread_stream(
|
||||
client=_client,
|
||||
thread_id=thread_id,
|
||||
assistant_id=assistant_id,
|
||||
additional_instructions=additional_instructions,
|
||||
instructions=instructions,
|
||||
metadata=metadata,
|
||||
model=model,
|
||||
tools=tools,
|
||||
event_handler=event_handler,
|
||||
)
|
||||
return self.arun_thread(
|
||||
thread_id=thread_id,
|
||||
assistant_id=assistant_id,
|
||||
|
|
@ -2588,6 +2697,19 @@ class OpenAIAssistantsAPI(BaseLLM):
|
|||
client=client,
|
||||
)
|
||||
|
||||
if stream is not None and stream == True:
|
||||
return self.run_thread_stream(
|
||||
client=openai_client,
|
||||
thread_id=thread_id,
|
||||
assistant_id=assistant_id,
|
||||
additional_instructions=additional_instructions,
|
||||
instructions=instructions,
|
||||
metadata=metadata,
|
||||
model=model,
|
||||
tools=tools,
|
||||
event_handler=event_handler,
|
||||
)
|
||||
|
||||
response = openai_client.beta.threads.runs.create_and_poll( # type: ignore
|
||||
thread_id=thread_id,
|
||||
assistant_id=assistant_id,
|
||||
|
|
|
|||
|
|
@ -1,11 +1,12 @@
|
|||
import os, types, traceback, copy
|
||||
import json
|
||||
from enum import Enum
|
||||
import types
|
||||
import traceback
|
||||
import copy
|
||||
import time
|
||||
from typing import Callable, Optional
|
||||
from litellm.utils import ModelResponse, get_secret, Choices, Message, Usage
|
||||
from litellm.utils import ModelResponse, Choices, Message, Usage
|
||||
import litellm
|
||||
import sys, httpx
|
||||
import httpx
|
||||
from litellm import verbose_logger
|
||||
|
||||
|
||||
class PalmError(Exception):
|
||||
|
|
@ -165,7 +166,10 @@ def completion(
|
|||
choices_list.append(choice_obj)
|
||||
model_response["choices"] = choices_list
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(
|
||||
"litellm.llms.palm.py::completion(): Exception occured - {}".format(str(e))
|
||||
)
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
raise PalmError(
|
||||
message=traceback.format_exc(), status_code=response.status_code
|
||||
)
|
||||
|
|
|
|||
|
|
@ -3,6 +3,7 @@
|
|||
|
||||
from functools import partial
|
||||
import os, types
|
||||
import traceback
|
||||
import json
|
||||
from enum import Enum
|
||||
import requests, copy # type: ignore
|
||||
|
|
@ -242,12 +243,12 @@ class PredibaseChatCompletion(BaseLLM):
|
|||
"details" in completion_response
|
||||
and "tokens" in completion_response["details"]
|
||||
):
|
||||
model_response.choices[0].finish_reason = completion_response[
|
||||
"details"
|
||||
]["finish_reason"]
|
||||
model_response.choices[0].finish_reason = map_finish_reason(
|
||||
completion_response["details"]["finish_reason"]
|
||||
)
|
||||
sum_logprob = 0
|
||||
for token in completion_response["details"]["tokens"]:
|
||||
if token["logprob"] != None:
|
||||
if token["logprob"] is not None:
|
||||
sum_logprob += token["logprob"]
|
||||
model_response["choices"][0][
|
||||
"message"
|
||||
|
|
@ -265,7 +266,7 @@ class PredibaseChatCompletion(BaseLLM):
|
|||
):
|
||||
sum_logprob = 0
|
||||
for token in item["tokens"]:
|
||||
if token["logprob"] != None:
|
||||
if token["logprob"] is not None:
|
||||
sum_logprob += token["logprob"]
|
||||
if len(item["generated_text"]) > 0:
|
||||
message_obj = Message(
|
||||
|
|
@ -275,7 +276,7 @@ class PredibaseChatCompletion(BaseLLM):
|
|||
else:
|
||||
message_obj = Message(content=None)
|
||||
choice_obj = Choices(
|
||||
finish_reason=item["finish_reason"],
|
||||
finish_reason=map_finish_reason(item["finish_reason"]),
|
||||
index=idx + 1,
|
||||
message=message_obj,
|
||||
)
|
||||
|
|
@ -285,10 +286,8 @@ class PredibaseChatCompletion(BaseLLM):
|
|||
## CALCULATING USAGE
|
||||
prompt_tokens = 0
|
||||
try:
|
||||
prompt_tokens = len(
|
||||
encoding.encode(model_response["choices"][0]["message"]["content"])
|
||||
) ##[TODO] use a model-specific tokenizer here
|
||||
except:
|
||||
prompt_tokens = litellm.token_counter(messages=messages)
|
||||
except Exception:
|
||||
# this should remain non blocking we should not block a response returning if calculating usage fails
|
||||
pass
|
||||
output_text = model_response["choices"][0]["message"].get("content", "")
|
||||
|
|
@ -331,6 +330,7 @@ class PredibaseChatCompletion(BaseLLM):
|
|||
logging_obj,
|
||||
optional_params: dict,
|
||||
tenant_id: str,
|
||||
timeout: Union[float, httpx.Timeout],
|
||||
acompletion=None,
|
||||
litellm_params=None,
|
||||
logger_fn=None,
|
||||
|
|
@ -340,6 +340,7 @@ class PredibaseChatCompletion(BaseLLM):
|
|||
completion_url = ""
|
||||
input_text = ""
|
||||
base_url = "https://serving.app.predibase.com"
|
||||
|
||||
if "https" in model:
|
||||
completion_url = model
|
||||
elif api_base:
|
||||
|
|
@ -349,7 +350,7 @@ class PredibaseChatCompletion(BaseLLM):
|
|||
|
||||
completion_url = f"{base_url}/{tenant_id}/deployments/v2/llms/{model}"
|
||||
|
||||
if optional_params.get("stream", False) == True:
|
||||
if optional_params.get("stream", False) is True:
|
||||
completion_url += "/generate_stream"
|
||||
else:
|
||||
completion_url += "/generate"
|
||||
|
|
@ -393,9 +394,9 @@ class PredibaseChatCompletion(BaseLLM):
|
|||
},
|
||||
)
|
||||
## COMPLETION CALL
|
||||
if acompletion == True:
|
||||
if acompletion is True:
|
||||
### ASYNC STREAMING
|
||||
if stream == True:
|
||||
if stream is True:
|
||||
return self.async_streaming(
|
||||
model=model,
|
||||
messages=messages,
|
||||
|
|
@ -410,6 +411,7 @@ class PredibaseChatCompletion(BaseLLM):
|
|||
litellm_params=litellm_params,
|
||||
logger_fn=logger_fn,
|
||||
headers=headers,
|
||||
timeout=timeout,
|
||||
) # type: ignore
|
||||
else:
|
||||
### ASYNC COMPLETION
|
||||
|
|
@ -428,10 +430,11 @@ class PredibaseChatCompletion(BaseLLM):
|
|||
litellm_params=litellm_params,
|
||||
logger_fn=logger_fn,
|
||||
headers=headers,
|
||||
timeout=timeout,
|
||||
) # type: ignore
|
||||
|
||||
### SYNC STREAMING
|
||||
if stream == True:
|
||||
if stream is True:
|
||||
response = requests.post(
|
||||
completion_url,
|
||||
headers=headers,
|
||||
|
|
@ -452,7 +455,6 @@ class PredibaseChatCompletion(BaseLLM):
|
|||
headers=headers,
|
||||
data=json.dumps(data),
|
||||
)
|
||||
|
||||
return self.process_response(
|
||||
model=model,
|
||||
response=response,
|
||||
|
|
@ -480,16 +482,26 @@ class PredibaseChatCompletion(BaseLLM):
|
|||
stream,
|
||||
data: dict,
|
||||
optional_params: dict,
|
||||
timeout: Union[float, httpx.Timeout],
|
||||
litellm_params=None,
|
||||
logger_fn=None,
|
||||
headers={},
|
||||
) -> ModelResponse:
|
||||
self.async_handler = AsyncHTTPHandler(
|
||||
timeout=httpx.Timeout(timeout=600.0, connect=5.0)
|
||||
)
|
||||
response = await self.async_handler.post(
|
||||
api_base, headers=headers, data=json.dumps(data)
|
||||
)
|
||||
|
||||
async_handler = AsyncHTTPHandler(timeout=httpx.Timeout(timeout=timeout))
|
||||
try:
|
||||
response = await async_handler.post(
|
||||
api_base, headers=headers, data=json.dumps(data)
|
||||
)
|
||||
except httpx.HTTPStatusError as e:
|
||||
raise PredibaseError(
|
||||
status_code=e.response.status_code,
|
||||
message="HTTPStatusError - {}".format(e.response.text),
|
||||
)
|
||||
except Exception as e:
|
||||
raise PredibaseError(
|
||||
status_code=500, message="{}\n{}".format(str(e), traceback.format_exc())
|
||||
)
|
||||
return self.process_response(
|
||||
model=model,
|
||||
response=response,
|
||||
|
|
@ -515,6 +527,7 @@ class PredibaseChatCompletion(BaseLLM):
|
|||
api_key,
|
||||
logging_obj,
|
||||
data: dict,
|
||||
timeout: Union[float, httpx.Timeout],
|
||||
optional_params=None,
|
||||
litellm_params=None,
|
||||
logger_fn=None,
|
||||
|
|
|
|||
|
|
@ -3,14 +3,7 @@ import requests, traceback
|
|||
import json, re, xml.etree.ElementTree as ET
|
||||
from jinja2 import Template, exceptions, meta, BaseLoader
|
||||
from jinja2.sandbox import ImmutableSandboxedEnvironment
|
||||
from typing import (
|
||||
Any,
|
||||
List,
|
||||
Mapping,
|
||||
MutableMapping,
|
||||
Optional,
|
||||
Sequence,
|
||||
)
|
||||
from typing import Any, List, Mapping, MutableMapping, Optional, Sequence, Tuple
|
||||
import litellm
|
||||
import litellm.types
|
||||
from litellm.types.completion import (
|
||||
|
|
@ -24,7 +17,7 @@ from litellm.types.completion import (
|
|||
import litellm.types.llms
|
||||
from litellm.types.llms.anthropic import *
|
||||
import uuid
|
||||
|
||||
from litellm.types.llms.bedrock import MessageBlock as BedrockMessageBlock
|
||||
import litellm.types.llms.vertex_ai
|
||||
|
||||
|
||||
|
|
@ -833,7 +826,7 @@ def anthropic_messages_pt_xml(messages: list):
|
|||
) # either string or none
|
||||
if messages[msg_i].get(
|
||||
"tool_calls", []
|
||||
): # support assistant tool invoke convertion
|
||||
): # support assistant tool invoke conversion
|
||||
assistant_text += convert_to_anthropic_tool_invoke_xml( # type: ignore
|
||||
messages[msg_i]["tool_calls"]
|
||||
)
|
||||
|
|
@ -1224,7 +1217,7 @@ def anthropic_messages_pt(messages: list):
|
|||
|
||||
if messages[msg_i].get(
|
||||
"tool_calls", []
|
||||
): # support assistant tool invoke convertion
|
||||
): # support assistant tool invoke conversion
|
||||
assistant_content.extend(
|
||||
convert_to_anthropic_tool_invoke(messages[msg_i]["tool_calls"])
|
||||
)
|
||||
|
|
@ -1460,9 +1453,7 @@ def _load_image_from_url(image_url):
|
|||
try:
|
||||
from PIL import Image
|
||||
except:
|
||||
raise Exception(
|
||||
"gemini image conversion failed please run `pip install Pillow`"
|
||||
)
|
||||
raise Exception("image conversion failed please run `pip install Pillow`")
|
||||
from io import BytesIO
|
||||
|
||||
try:
|
||||
|
|
@ -1613,6 +1604,380 @@ def azure_text_pt(messages: list):
|
|||
return prompt
|
||||
|
||||
|
||||
###### AMAZON BEDROCK #######
|
||||
|
||||
from litellm.types.llms.bedrock import (
|
||||
ToolResultContentBlock as BedrockToolResultContentBlock,
|
||||
ToolResultBlock as BedrockToolResultBlock,
|
||||
ToolConfigBlock as BedrockToolConfigBlock,
|
||||
ToolUseBlock as BedrockToolUseBlock,
|
||||
ImageSourceBlock as BedrockImageSourceBlock,
|
||||
ImageBlock as BedrockImageBlock,
|
||||
ContentBlock as BedrockContentBlock,
|
||||
ToolInputSchemaBlock as BedrockToolInputSchemaBlock,
|
||||
ToolSpecBlock as BedrockToolSpecBlock,
|
||||
ToolBlock as BedrockToolBlock,
|
||||
ToolChoiceValuesBlock as BedrockToolChoiceValuesBlock,
|
||||
)
|
||||
|
||||
|
||||
def get_image_details(image_url) -> Tuple[str, str]:
|
||||
try:
|
||||
import base64
|
||||
|
||||
# Send a GET request to the image URL
|
||||
response = requests.get(image_url)
|
||||
response.raise_for_status() # Raise an exception for HTTP errors
|
||||
|
||||
# Check the response's content type to ensure it is an image
|
||||
content_type = response.headers.get("content-type")
|
||||
if not content_type or "image" not in content_type:
|
||||
raise ValueError(
|
||||
f"URL does not point to a valid image (content-type: {content_type})"
|
||||
)
|
||||
|
||||
# Convert the image content to base64 bytes
|
||||
base64_bytes = base64.b64encode(response.content).decode("utf-8")
|
||||
|
||||
# Get mime-type
|
||||
mime_type = content_type.split("/")[
|
||||
1
|
||||
] # Extract mime-type from content-type header
|
||||
|
||||
return base64_bytes, mime_type
|
||||
|
||||
except requests.RequestException as e:
|
||||
raise Exception(f"Request failed: {e}")
|
||||
except Exception as e:
|
||||
raise e
|
||||
|
||||
|
||||
def _process_bedrock_converse_image_block(image_url: str) -> BedrockImageBlock:
|
||||
if "base64" in image_url:
|
||||
# Case 1: Images with base64 encoding
|
||||
import base64, re
|
||||
|
||||
# base 64 is passed as data:image/jpeg;base64,<base-64-encoded-image>
|
||||
image_metadata, img_without_base_64 = image_url.split(",")
|
||||
|
||||
# read mime_type from img_without_base_64=data:image/jpeg;base64
|
||||
# Extract MIME type using regular expression
|
||||
mime_type_match = re.match(r"data:(.*?);base64", image_metadata)
|
||||
if mime_type_match:
|
||||
mime_type = mime_type_match.group(1)
|
||||
image_format = mime_type.split("/")[1]
|
||||
else:
|
||||
mime_type = "image/jpeg"
|
||||
image_format = "jpeg"
|
||||
_blob = BedrockImageSourceBlock(bytes=img_without_base_64)
|
||||
supported_image_formats = (
|
||||
litellm.AmazonConverseConfig().get_supported_image_types()
|
||||
)
|
||||
if image_format in supported_image_formats:
|
||||
return BedrockImageBlock(source=_blob, format=image_format) # type: ignore
|
||||
else:
|
||||
# Handle the case when the image format is not supported
|
||||
raise ValueError(
|
||||
"Unsupported image format: {}. Supported formats: {}".format(
|
||||
image_format, supported_image_formats
|
||||
)
|
||||
)
|
||||
elif "https:/" in image_url:
|
||||
# Case 2: Images with direct links
|
||||
image_bytes, image_format = get_image_details(image_url)
|
||||
_blob = BedrockImageSourceBlock(bytes=image_bytes)
|
||||
supported_image_formats = (
|
||||
litellm.AmazonConverseConfig().get_supported_image_types()
|
||||
)
|
||||
if image_format in supported_image_formats:
|
||||
return BedrockImageBlock(source=_blob, format=image_format) # type: ignore
|
||||
else:
|
||||
# Handle the case when the image format is not supported
|
||||
raise ValueError(
|
||||
"Unsupported image format: {}. Supported formats: {}".format(
|
||||
image_format, supported_image_formats
|
||||
)
|
||||
)
|
||||
else:
|
||||
raise ValueError(
|
||||
"Unsupported image type. Expected either image url or base64 encoded string - \
|
||||
e.g. 'data:image/jpeg;base64,<base64-encoded-string>'"
|
||||
)
|
||||
|
||||
|
||||
def _convert_to_bedrock_tool_call_invoke(
|
||||
tool_calls: list,
|
||||
) -> List[BedrockContentBlock]:
|
||||
"""
|
||||
OpenAI tool invokes:
|
||||
{
|
||||
"role": "assistant",
|
||||
"content": null,
|
||||
"tool_calls": [
|
||||
{
|
||||
"id": "call_abc123",
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_current_weather",
|
||||
"arguments": "{\n\"location\": \"Boston, MA\"\n}"
|
||||
}
|
||||
}
|
||||
]
|
||||
},
|
||||
"""
|
||||
"""
|
||||
Bedrock tool invokes:
|
||||
[
|
||||
{
|
||||
"role": "assistant",
|
||||
"toolUse": {
|
||||
"input": {"location": "Boston, MA", ..},
|
||||
"name": "get_current_weather",
|
||||
"toolUseId": "call_abc123"
|
||||
}
|
||||
}
|
||||
]
|
||||
"""
|
||||
"""
|
||||
- json.loads argument
|
||||
- extract name
|
||||
- extract id
|
||||
"""
|
||||
|
||||
try:
|
||||
_parts_list: List[BedrockContentBlock] = []
|
||||
for tool in tool_calls:
|
||||
if "function" in tool:
|
||||
id = tool["id"]
|
||||
name = tool["function"].get("name", "")
|
||||
arguments = tool["function"].get("arguments", "")
|
||||
arguments_dict = json.loads(arguments)
|
||||
bedrock_tool = BedrockToolUseBlock(
|
||||
input=arguments_dict, name=name, toolUseId=id
|
||||
)
|
||||
bedrock_content_block = BedrockContentBlock(toolUse=bedrock_tool)
|
||||
_parts_list.append(bedrock_content_block)
|
||||
return _parts_list
|
||||
except Exception as e:
|
||||
raise Exception(
|
||||
"Unable to convert openai tool calls={} to bedrock tool calls. Received error={}".format(
|
||||
tool_calls, str(e)
|
||||
)
|
||||
)
|
||||
|
||||
|
||||
def _convert_to_bedrock_tool_call_result(
|
||||
message: dict,
|
||||
) -> BedrockMessageBlock:
|
||||
"""
|
||||
OpenAI message with a tool result looks like:
|
||||
{
|
||||
"tool_call_id": "tool_1",
|
||||
"role": "tool",
|
||||
"name": "get_current_weather",
|
||||
"content": "function result goes here",
|
||||
},
|
||||
|
||||
OpenAI message with a function call result looks like:
|
||||
{
|
||||
"role": "function",
|
||||
"name": "get_current_weather",
|
||||
"content": "function result goes here",
|
||||
}
|
||||
"""
|
||||
"""
|
||||
Bedrock result looks like this:
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{
|
||||
"toolResult": {
|
||||
"toolUseId": "tooluse_kZJMlvQmRJ6eAyJE5GIl7Q",
|
||||
"content": [
|
||||
{
|
||||
"json": {
|
||||
"song": "Elemental Hotel",
|
||||
"artist": "8 Storey Hike"
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
"""
|
||||
"""
|
||||
-
|
||||
"""
|
||||
content = message.get("content", "")
|
||||
name = message.get("name", "")
|
||||
id = message.get("tool_call_id", str(uuid.uuid4()))
|
||||
|
||||
tool_result_content_block = BedrockToolResultContentBlock(text=content)
|
||||
tool_result = BedrockToolResultBlock(
|
||||
content=[tool_result_content_block],
|
||||
toolUseId=id,
|
||||
)
|
||||
content_block = BedrockContentBlock(toolResult=tool_result)
|
||||
|
||||
return BedrockMessageBlock(role="user", content=[content_block])
|
||||
|
||||
|
||||
def _bedrock_converse_messages_pt(messages: List) -> List[BedrockMessageBlock]:
|
||||
"""
|
||||
Converts given messages from OpenAI format to Bedrock format
|
||||
|
||||
- Roles must alternate b/w 'user' and 'model' (same as anthropic -> merge consecutive roles)
|
||||
- Please ensure that function response turn comes immediately after a function call turn
|
||||
"""
|
||||
|
||||
contents: List[BedrockMessageBlock] = []
|
||||
msg_i = 0
|
||||
while msg_i < len(messages):
|
||||
user_content: List[BedrockContentBlock] = []
|
||||
init_msg_i = msg_i
|
||||
## MERGE CONSECUTIVE USER CONTENT ##
|
||||
while msg_i < len(messages) and messages[msg_i]["role"] == "user":
|
||||
if isinstance(messages[msg_i]["content"], list):
|
||||
_parts: List[BedrockContentBlock] = []
|
||||
for element in messages[msg_i]["content"]:
|
||||
if isinstance(element, dict):
|
||||
if element["type"] == "text":
|
||||
_part = BedrockContentBlock(text=element["text"])
|
||||
_parts.append(_part)
|
||||
elif element["type"] == "image_url":
|
||||
image_url = element["image_url"]["url"]
|
||||
_part = _process_bedrock_converse_image_block( # type: ignore
|
||||
image_url=image_url
|
||||
)
|
||||
_parts.append(BedrockContentBlock(image=_part)) # type: ignore
|
||||
user_content.extend(_parts)
|
||||
else:
|
||||
_part = BedrockContentBlock(text=messages[msg_i]["content"])
|
||||
user_content.append(_part)
|
||||
|
||||
msg_i += 1
|
||||
|
||||
if user_content:
|
||||
contents.append(BedrockMessageBlock(role="user", content=user_content))
|
||||
assistant_content: List[BedrockContentBlock] = []
|
||||
## MERGE CONSECUTIVE ASSISTANT CONTENT ##
|
||||
while msg_i < len(messages) and messages[msg_i]["role"] == "assistant":
|
||||
if isinstance(messages[msg_i]["content"], list):
|
||||
assistants_parts: List[BedrockContentBlock] = []
|
||||
for element in messages[msg_i]["content"]:
|
||||
if isinstance(element, dict):
|
||||
if element["type"] == "text":
|
||||
assistants_part = BedrockContentBlock(text=element["text"])
|
||||
assistants_parts.append(assistants_part)
|
||||
elif element["type"] == "image_url":
|
||||
image_url = element["image_url"]["url"]
|
||||
assistants_part = _process_bedrock_converse_image_block( # type: ignore
|
||||
image_url=image_url
|
||||
)
|
||||
assistants_parts.append(
|
||||
BedrockContentBlock(image=assistants_part) # type: ignore
|
||||
)
|
||||
assistant_content.extend(assistants_parts)
|
||||
elif messages[msg_i].get(
|
||||
"tool_calls", []
|
||||
): # support assistant tool invoke convertion
|
||||
assistant_content.extend(
|
||||
_convert_to_bedrock_tool_call_invoke(messages[msg_i]["tool_calls"])
|
||||
)
|
||||
else:
|
||||
assistant_text = (
|
||||
messages[msg_i].get("content") or ""
|
||||
) # either string or none
|
||||
if assistant_text:
|
||||
assistant_content.append(BedrockContentBlock(text=assistant_text))
|
||||
|
||||
msg_i += 1
|
||||
|
||||
if assistant_content:
|
||||
contents.append(
|
||||
BedrockMessageBlock(role="assistant", content=assistant_content)
|
||||
)
|
||||
|
||||
## APPEND TOOL CALL MESSAGES ##
|
||||
if msg_i < len(messages) and messages[msg_i]["role"] == "tool":
|
||||
tool_call_result = _convert_to_bedrock_tool_call_result(messages[msg_i])
|
||||
contents.append(tool_call_result)
|
||||
msg_i += 1
|
||||
if msg_i == init_msg_i: # prevent infinite loops
|
||||
raise Exception(
|
||||
"Invalid Message passed in - {}. File an issue https://github.com/BerriAI/litellm/issues".format(
|
||||
messages[msg_i]
|
||||
)
|
||||
)
|
||||
|
||||
return contents
|
||||
|
||||
|
||||
def _bedrock_tools_pt(tools: List) -> List[BedrockToolBlock]:
|
||||
"""
|
||||
OpenAI tools looks like:
|
||||
tools = [
|
||||
{
|
||||
"type": "function",
|
||||
"function": {
|
||||
"name": "get_current_weather",
|
||||
"description": "Get the current weather in a given location",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {
|
||||
"type": "string",
|
||||
"description": "The city and state, e.g. San Francisco, CA",
|
||||
},
|
||||
"unit": {"type": "string", "enum": ["celsius", "fahrenheit"]},
|
||||
},
|
||||
"required": ["location"],
|
||||
},
|
||||
}
|
||||
}
|
||||
]
|
||||
"""
|
||||
"""
|
||||
Bedrock toolConfig looks like:
|
||||
"tools": [
|
||||
{
|
||||
"toolSpec": {
|
||||
"name": "top_song",
|
||||
"description": "Get the most popular song played on a radio station.",
|
||||
"inputSchema": {
|
||||
"json": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"sign": {
|
||||
"type": "string",
|
||||
"description": "The call sign for the radio station for which you want the most popular song. Example calls signs are WZPZ, and WKRP."
|
||||
}
|
||||
},
|
||||
"required": [
|
||||
"sign"
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
]
|
||||
"""
|
||||
tool_block_list: List[BedrockToolBlock] = []
|
||||
for tool in tools:
|
||||
parameters = tool.get("function", {}).get("parameters", None)
|
||||
name = tool.get("function", {}).get("name", "")
|
||||
description = tool.get("function", {}).get("description", "")
|
||||
tool_input_schema = BedrockToolInputSchemaBlock(json=parameters)
|
||||
tool_spec = BedrockToolSpecBlock(
|
||||
inputSchema=tool_input_schema, name=name, description=description
|
||||
)
|
||||
tool_block = BedrockToolBlock(toolSpec=tool_spec)
|
||||
tool_block_list.append(tool_block)
|
||||
|
||||
return tool_block_list
|
||||
|
||||
|
||||
# Function call template
|
||||
def function_call_prompt(messages: list, functions: list):
|
||||
function_prompt = """Produce JSON OUTPUT ONLY! Adhere to this format {"name": "function_name", "arguments":{"argument_name": "argument_value"}} The following functions are available to you:"""
|
||||
|
|
|
|||
|
|
@ -12,6 +12,7 @@ from litellm.llms.prompt_templates.factory import (
|
|||
convert_to_gemini_tool_call_result,
|
||||
convert_to_gemini_tool_call_invoke,
|
||||
)
|
||||
from litellm.types.files import get_file_mime_type_for_file_type, get_file_type_from_extension, is_gemini_1_5_accepted_file_type, is_video_file_type
|
||||
|
||||
|
||||
class VertexAIError(Exception):
|
||||
|
|
@ -297,24 +298,31 @@ def _convert_gemini_role(role: str) -> Literal["user", "model"]:
|
|||
|
||||
def _process_gemini_image(image_url: str) -> PartType:
|
||||
try:
|
||||
# GCS URIs
|
||||
if "gs://" in image_url:
|
||||
# Case 1: Images with Cloud Storage URIs
|
||||
# The supported MIME types for images include image/png and image/jpeg.
|
||||
part_mime = "image/png" if "png" in image_url else "image/jpeg"
|
||||
_file_data = FileDataType(mime_type=part_mime, file_uri=image_url)
|
||||
return PartType(file_data=_file_data)
|
||||
# Figure out file type
|
||||
extension_with_dot = os.path.splitext(image_url)[-1] # Ex: ".png"
|
||||
extension = extension_with_dot[1:] # Ex: "png"
|
||||
|
||||
file_type = get_file_type_from_extension(extension)
|
||||
|
||||
# Validate the file type is supported by Gemini
|
||||
if not is_gemini_1_5_accepted_file_type(file_type):
|
||||
raise Exception(f"File type not supported by gemini - {file_type}")
|
||||
|
||||
mime_type = get_file_mime_type_for_file_type(file_type)
|
||||
file_data = FileDataType(mime_type=mime_type, file_uri=image_url)
|
||||
|
||||
return PartType(file_data=file_data)
|
||||
|
||||
# Direct links
|
||||
elif "https:/" in image_url:
|
||||
# Case 2: Images with direct links
|
||||
image = _load_image_from_url(image_url)
|
||||
_blob = BlobType(data=image.data, mime_type=image._mime_type)
|
||||
return PartType(inline_data=_blob)
|
||||
elif ".mp4" in image_url and "gs://" in image_url:
|
||||
# Case 3: Videos with Cloud Storage URIs
|
||||
part_mime = "video/mp4"
|
||||
_file_data = FileDataType(mime_type=part_mime, file_uri=image_url)
|
||||
return PartType(file_data=_file_data)
|
||||
|
||||
# Base64 encoding
|
||||
elif "base64" in image_url:
|
||||
# Case 4: Images with base64 encoding
|
||||
import base64, re
|
||||
|
||||
# base 64 is passed as data:image/jpeg;base64,<base-64-encoded-image>
|
||||
|
|
@ -390,7 +398,7 @@ def _gemini_convert_messages_with_history(messages: list) -> List[ContentType]:
|
|||
assistant_content.extend(_parts)
|
||||
elif messages[msg_i].get(
|
||||
"tool_calls", []
|
||||
): # support assistant tool invoke convertion
|
||||
): # support assistant tool invoke conversion
|
||||
assistant_content.extend(
|
||||
convert_to_gemini_tool_call_invoke(messages[msg_i]["tool_calls"])
|
||||
)
|
||||
|
|
@ -421,112 +429,6 @@ def _gemini_convert_messages_with_history(messages: list) -> List[ContentType]:
|
|||
return contents
|
||||
|
||||
|
||||
def _gemini_vision_convert_messages(messages: list):
|
||||
"""
|
||||
Converts given messages for GPT-4 Vision to Gemini format.
|
||||
|
||||
Args:
|
||||
messages (list): The messages to convert. Each message can be a dictionary with a "content" key. The content can be a string or a list of elements. If it is a string, it will be concatenated to the prompt. If it is a list, each element will be processed based on its type:
|
||||
- If the element is a dictionary with a "type" key equal to "text", its "text" value will be concatenated to the prompt.
|
||||
- If the element is a dictionary with a "type" key equal to "image_url", its "image_url" value will be added to the list of images.
|
||||
|
||||
Returns:
|
||||
tuple: A tuple containing the prompt (a string) and the processed images (a list of objects representing the images).
|
||||
|
||||
Raises:
|
||||
VertexAIError: If the import of the 'vertexai' module fails, indicating that 'google-cloud-aiplatform' needs to be installed.
|
||||
Exception: If any other exception occurs during the execution of the function.
|
||||
|
||||
Note:
|
||||
This function is based on the code from the 'gemini/getting-started/intro_gemini_python.ipynb' notebook in the 'generative-ai' repository on GitHub.
|
||||
The supported MIME types for images include 'image/png' and 'image/jpeg'.
|
||||
|
||||
Examples:
|
||||
>>> messages = [
|
||||
... {"content": "Hello, world!"},
|
||||
... {"content": [{"type": "text", "text": "This is a text message."}, {"type": "image_url", "image_url": "example.com/image.png"}]},
|
||||
... ]
|
||||
>>> _gemini_vision_convert_messages(messages)
|
||||
('Hello, world!This is a text message.', [<Part object>, <Part object>])
|
||||
"""
|
||||
try:
|
||||
import vertexai
|
||||
except:
|
||||
raise VertexAIError(
|
||||
status_code=400,
|
||||
message="vertexai import failed please run `pip install google-cloud-aiplatform`",
|
||||
)
|
||||
try:
|
||||
from vertexai.preview.language_models import (
|
||||
ChatModel,
|
||||
CodeChatModel,
|
||||
InputOutputTextPair,
|
||||
)
|
||||
from vertexai.language_models import TextGenerationModel, CodeGenerationModel
|
||||
from vertexai.preview.generative_models import (
|
||||
GenerativeModel,
|
||||
Part,
|
||||
GenerationConfig,
|
||||
Image,
|
||||
)
|
||||
|
||||
# given messages for gpt-4 vision, convert them for gemini
|
||||
# https://github.com/GoogleCloudPlatform/generative-ai/blob/main/gemini/getting-started/intro_gemini_python.ipynb
|
||||
prompt = ""
|
||||
images = []
|
||||
for message in messages:
|
||||
if isinstance(message["content"], str):
|
||||
prompt += message["content"]
|
||||
elif isinstance(message["content"], list):
|
||||
# see https://docs.litellm.ai/docs/providers/openai#openai-vision-models
|
||||
for element in message["content"]:
|
||||
if isinstance(element, dict):
|
||||
if element["type"] == "text":
|
||||
prompt += element["text"]
|
||||
elif element["type"] == "image_url":
|
||||
image_url = element["image_url"]["url"]
|
||||
images.append(image_url)
|
||||
# processing images passed to gemini
|
||||
processed_images = []
|
||||
for img in images:
|
||||
if "gs://" in img:
|
||||
# Case 1: Images with Cloud Storage URIs
|
||||
# The supported MIME types for images include image/png and image/jpeg.
|
||||
part_mime = "image/png" if "png" in img else "image/jpeg"
|
||||
google_clooud_part = Part.from_uri(img, mime_type=part_mime)
|
||||
processed_images.append(google_clooud_part)
|
||||
elif "https:/" in img:
|
||||
# Case 2: Images with direct links
|
||||
image = _load_image_from_url(img)
|
||||
processed_images.append(image)
|
||||
elif ".mp4" in img and "gs://" in img:
|
||||
# Case 3: Videos with Cloud Storage URIs
|
||||
part_mime = "video/mp4"
|
||||
google_clooud_part = Part.from_uri(img, mime_type=part_mime)
|
||||
processed_images.append(google_clooud_part)
|
||||
elif "base64" in img:
|
||||
# Case 4: Images with base64 encoding
|
||||
import base64, re
|
||||
|
||||
# base 64 is passed as data:image/jpeg;base64,<base-64-encoded-image>
|
||||
image_metadata, img_without_base_64 = img.split(",")
|
||||
|
||||
# read mime_type from img_without_base_64=data:image/jpeg;base64
|
||||
# Extract MIME type using regular expression
|
||||
mime_type_match = re.match(r"data:(.*?);base64", image_metadata)
|
||||
|
||||
if mime_type_match:
|
||||
mime_type = mime_type_match.group(1)
|
||||
else:
|
||||
mime_type = "image/jpeg"
|
||||
decoded_img = base64.b64decode(img_without_base_64)
|
||||
processed_image = Part.from_data(data=decoded_img, mime_type=mime_type)
|
||||
processed_images.append(processed_image)
|
||||
return prompt, processed_images
|
||||
except Exception as e:
|
||||
raise e
|
||||
|
||||
|
||||
def _get_client_cache_key(model: str, vertex_project: str, vertex_location: str):
|
||||
_cache_key = f"{model}-{vertex_project}-{vertex_location}"
|
||||
return _cache_key
|
||||
|
|
@ -642,9 +544,9 @@ def completion(
|
|||
|
||||
prompt = " ".join(
|
||||
[
|
||||
message["content"]
|
||||
message.get("content")
|
||||
for message in messages
|
||||
if isinstance(message["content"], str)
|
||||
if isinstance(message.get("content", None), str)
|
||||
]
|
||||
)
|
||||
|
||||
|
|
|
|||
111
litellm/main.py
|
|
@ -14,6 +14,7 @@ from functools import partial
|
|||
import dotenv, traceback, random, asyncio, time, contextvars
|
||||
from copy import deepcopy
|
||||
import httpx
|
||||
|
||||
import litellm
|
||||
from ._logging import verbose_logger
|
||||
from litellm import ( # type: ignore
|
||||
|
|
@ -78,7 +79,7 @@ from .llms.anthropic import AnthropicChatCompletion
|
|||
from .llms.anthropic_text import AnthropicTextCompletion
|
||||
from .llms.huggingface_restapi import Huggingface
|
||||
from .llms.predibase import PredibaseChatCompletion
|
||||
from .llms.bedrock_httpx import BedrockLLM
|
||||
from .llms.bedrock_httpx import BedrockLLM, BedrockConverseLLM
|
||||
from .llms.vertex_httpx import VertexLLM
|
||||
from .llms.triton import TritonChatCompletion
|
||||
from .llms.prompt_templates.factory import (
|
||||
|
|
@ -121,6 +122,7 @@ huggingface = Huggingface()
|
|||
predibase_chat_completions = PredibaseChatCompletion()
|
||||
triton_chat_completions = TritonChatCompletion()
|
||||
bedrock_chat_completion = BedrockLLM()
|
||||
bedrock_converse_chat_completion = BedrockConverseLLM()
|
||||
vertex_chat_completion = VertexLLM()
|
||||
####### COMPLETION ENDPOINTS ################
|
||||
|
||||
|
|
@ -223,7 +225,7 @@ async def acompletion(
|
|||
extra_headers: Optional[dict] = None,
|
||||
# Optional liteLLM function params
|
||||
**kwargs,
|
||||
):
|
||||
) -> Union[ModelResponse, CustomStreamWrapper]:
|
||||
"""
|
||||
Asynchronously executes a litellm.completion() call for any of litellm supported llms (example gpt-4, gpt-3.5-turbo, claude-2, command-nightly)
|
||||
|
||||
|
|
@ -339,6 +341,8 @@ async def acompletion(
|
|||
if isinstance(init_response, dict) or isinstance(
|
||||
init_response, ModelResponse
|
||||
): ## CACHING SCENARIO
|
||||
if isinstance(init_response, dict):
|
||||
response = ModelResponse(**init_response)
|
||||
response = init_response
|
||||
elif asyncio.iscoroutine(init_response):
|
||||
response = await init_response
|
||||
|
|
@ -361,7 +365,10 @@ async def acompletion(
|
|||
) # sets the logging event loop if the user does sync streaming (e.g. on proxy for sagemaker calls)
|
||||
return response
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(
|
||||
"litellm.acompletion(): Exception occured - {}".format(str(e))
|
||||
)
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
custom_llm_provider = custom_llm_provider or "openai"
|
||||
raise exception_type(
|
||||
model=model,
|
||||
|
|
@ -425,9 +432,9 @@ def mock_completion(
|
|||
if isinstance(mock_response, openai.APIError):
|
||||
raise mock_response
|
||||
raise litellm.APIError(
|
||||
status_code=500, # type: ignore
|
||||
message=str(mock_response),
|
||||
llm_provider="openai", # type: ignore
|
||||
status_code=getattr(mock_response, "status_code", 500), # type: ignore
|
||||
message=getattr(mock_response, "text", str(mock_response)),
|
||||
llm_provider=getattr(mock_response, "llm_provider", "openai"), # type: ignore
|
||||
model=model, # type: ignore
|
||||
request=httpx.Request(method="POST", url="https://api.openai.com/v1/"),
|
||||
)
|
||||
|
|
@ -465,16 +472,25 @@ def mock_completion(
|
|||
try:
|
||||
_, custom_llm_provider, _, _ = litellm.utils.get_llm_provider(model=model)
|
||||
model_response._hidden_params["custom_llm_provider"] = custom_llm_provider
|
||||
except:
|
||||
except Exception:
|
||||
# dont let setting a hidden param block a mock_respose
|
||||
pass
|
||||
|
||||
if logging is not None:
|
||||
logging.post_call(
|
||||
input=messages,
|
||||
api_key="my-secret-key",
|
||||
original_response="my-original-response",
|
||||
)
|
||||
return model_response
|
||||
|
||||
except Exception as e:
|
||||
if isinstance(e, openai.APIError):
|
||||
raise e
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(
|
||||
"litellm.mock_completion(): Exception occured - {}".format(str(e))
|
||||
)
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
raise Exception("Mock completion response failed")
|
||||
|
||||
|
||||
|
|
@ -835,6 +851,7 @@ def completion(
|
|||
logprobs=logprobs,
|
||||
top_logprobs=top_logprobs,
|
||||
extra_headers=extra_headers,
|
||||
api_version=api_version,
|
||||
**non_default_params,
|
||||
)
|
||||
|
||||
|
|
@ -1932,7 +1949,8 @@ def completion(
|
|||
)
|
||||
|
||||
api_base = (
|
||||
optional_params.pop("api_base", None)
|
||||
api_base
|
||||
or optional_params.pop("api_base", None)
|
||||
or optional_params.pop("base_url", None)
|
||||
or litellm.api_base
|
||||
or get_secret("PREDIBASE_API_BASE")
|
||||
|
|
@ -1960,12 +1978,13 @@ def completion(
|
|||
custom_prompt_dict=custom_prompt_dict,
|
||||
api_key=api_key,
|
||||
tenant_id=tenant_id,
|
||||
timeout=timeout,
|
||||
)
|
||||
|
||||
if (
|
||||
"stream" in optional_params
|
||||
and optional_params["stream"] == True
|
||||
and acompletion == False
|
||||
and optional_params["stream"] is True
|
||||
and acompletion is False
|
||||
):
|
||||
return _model_response
|
||||
response = _model_response
|
||||
|
|
@ -2093,22 +2112,40 @@ def completion(
|
|||
logging_obj=logging,
|
||||
)
|
||||
else:
|
||||
response = bedrock_chat_completion.completion(
|
||||
model=model,
|
||||
messages=messages,
|
||||
custom_prompt_dict=custom_prompt_dict,
|
||||
model_response=model_response,
|
||||
print_verbose=print_verbose,
|
||||
optional_params=optional_params,
|
||||
litellm_params=litellm_params,
|
||||
logger_fn=logger_fn,
|
||||
encoding=encoding,
|
||||
logging_obj=logging,
|
||||
extra_headers=extra_headers,
|
||||
timeout=timeout,
|
||||
acompletion=acompletion,
|
||||
client=client,
|
||||
)
|
||||
if model.startswith("anthropic"):
|
||||
response = bedrock_converse_chat_completion.completion(
|
||||
model=model,
|
||||
messages=messages,
|
||||
custom_prompt_dict=custom_prompt_dict,
|
||||
model_response=model_response,
|
||||
print_verbose=print_verbose,
|
||||
optional_params=optional_params,
|
||||
litellm_params=litellm_params,
|
||||
logger_fn=logger_fn,
|
||||
encoding=encoding,
|
||||
logging_obj=logging,
|
||||
extra_headers=extra_headers,
|
||||
timeout=timeout,
|
||||
acompletion=acompletion,
|
||||
client=client,
|
||||
)
|
||||
else:
|
||||
response = bedrock_chat_completion.completion(
|
||||
model=model,
|
||||
messages=messages,
|
||||
custom_prompt_dict=custom_prompt_dict,
|
||||
model_response=model_response,
|
||||
print_verbose=print_verbose,
|
||||
optional_params=optional_params,
|
||||
litellm_params=litellm_params,
|
||||
logger_fn=logger_fn,
|
||||
encoding=encoding,
|
||||
logging_obj=logging,
|
||||
extra_headers=extra_headers,
|
||||
timeout=timeout,
|
||||
acompletion=acompletion,
|
||||
client=client,
|
||||
)
|
||||
if optional_params.get("stream", False):
|
||||
## LOGGING
|
||||
logging.post_call(
|
||||
|
|
@ -2411,6 +2448,7 @@ def completion(
|
|||
"top_k": kwargs.get("top_k", 40),
|
||||
},
|
||||
},
|
||||
verify=litellm.ssl_verify,
|
||||
)
|
||||
response_json = resp.json()
|
||||
"""
|
||||
|
|
@ -3720,7 +3758,7 @@ async def amoderation(input: str, model: str, api_key: Optional[str] = None, **k
|
|||
|
||||
##### Image Generation #######################
|
||||
@client
|
||||
async def aimage_generation(*args, **kwargs):
|
||||
async def aimage_generation(*args, **kwargs) -> ImageResponse:
|
||||
"""
|
||||
Asynchronously calls the `image_generation` function with the given arguments and keyword arguments.
|
||||
|
||||
|
|
@ -3753,6 +3791,8 @@ async def aimage_generation(*args, **kwargs):
|
|||
if isinstance(init_response, dict) or isinstance(
|
||||
init_response, ImageResponse
|
||||
): ## CACHING SCENARIO
|
||||
if isinstance(init_response, dict):
|
||||
init_response = ImageResponse(**init_response)
|
||||
response = init_response
|
||||
elif asyncio.iscoroutine(init_response):
|
||||
response = await init_response
|
||||
|
|
@ -3788,7 +3828,7 @@ def image_generation(
|
|||
litellm_logging_obj=None,
|
||||
custom_llm_provider=None,
|
||||
**kwargs,
|
||||
):
|
||||
) -> ImageResponse:
|
||||
"""
|
||||
Maps the https://api.openai.com/v1/images/generations endpoint.
|
||||
|
||||
|
|
@ -4120,7 +4160,7 @@ def transcription(
|
|||
or litellm.api_key
|
||||
or litellm.azure_key
|
||||
or get_secret("AZURE_API_KEY")
|
||||
)
|
||||
) # type: ignore
|
||||
|
||||
response = azure_chat_completions.audio_transcriptions(
|
||||
model=model,
|
||||
|
|
@ -4329,6 +4369,10 @@ async def ahealth_check(
|
|||
mode = litellm.model_cost[model]["mode"]
|
||||
|
||||
model, custom_llm_provider, _, _ = get_llm_provider(model=model)
|
||||
|
||||
if model in litellm.model_cost and mode is None:
|
||||
mode = litellm.model_cost[model]["mode"]
|
||||
|
||||
mode = mode or "chat" # default to chat completion calls
|
||||
|
||||
if custom_llm_provider == "azure":
|
||||
|
|
@ -4419,7 +4463,10 @@ async def ahealth_check(
|
|||
response = {} # args like remaining ratelimit etc.
|
||||
return response
|
||||
except Exception as e:
|
||||
traceback.print_exc()
|
||||
verbose_logger.error(
|
||||
"litellm.ahealth_check(): Exception occured - {}".format(str(e))
|
||||
)
|
||||
verbose_logger.debug(traceback.format_exc())
|
||||
stack_trace = traceback.format_exc()
|
||||
if isinstance(stack_trace, str):
|
||||
stack_trace = stack_trace[:1000]
|
||||
|
|
@ -4525,7 +4572,7 @@ def stream_chunk_builder_text_completion(chunks: list, messages: Optional[List]
|
|||
|
||||
def stream_chunk_builder(
|
||||
chunks: list, messages: Optional[list] = None, start_time=None, end_time=None
|
||||
):
|
||||
) -> Union[ModelResponse, TextCompletionResponse]:
|
||||
model_response = litellm.ModelResponse()
|
||||
### SORT CHUNKS BASED ON CREATED ORDER ##
|
||||
print_verbose("Goes into checking if chunk has hiddden created at param")
|
||||
|
|
|
|||
|
|
@ -1500,7 +1500,7 @@
|
|||
"max_pdf_size_mb": 30,
|
||||
"input_cost_per_token": 0,
|
||||
"output_cost_per_token": 0,
|
||||
"litellm_provider": "vertex_ai-language-models",
|
||||
"litellm_provider": "gemini",
|
||||
"mode": "chat",
|
||||
"supports_function_calling": true,
|
||||
"supports_vision": true,
|
||||
|
|
@ -3009,32 +3009,37 @@
|
|||
"litellm_provider": "sagemaker",
|
||||
"mode": "chat"
|
||||
},
|
||||
"together-ai-up-to-3b": {
|
||||
"together-ai-up-to-4b": {
|
||||
"input_cost_per_token": 0.0000001,
|
||||
"output_cost_per_token": 0.0000001,
|
||||
"litellm_provider": "together_ai"
|
||||
},
|
||||
"together-ai-3.1b-7b": {
|
||||
"together-ai-4.1b-8b": {
|
||||
"input_cost_per_token": 0.0000002,
|
||||
"output_cost_per_token": 0.0000002,
|
||||
"litellm_provider": "together_ai"
|
||||
},
|
||||
"together-ai-7.1b-20b": {
|
||||
"together-ai-8.1b-21b": {
|
||||
"max_tokens": 1000,
|
||||
"input_cost_per_token": 0.0000004,
|
||||
"output_cost_per_token": 0.0000004,
|
||||
"input_cost_per_token": 0.0000003,
|
||||
"output_cost_per_token": 0.0000003,
|
||||
"litellm_provider": "together_ai"
|
||||
},
|
||||
"together-ai-20.1b-40b": {
|
||||
"together-ai-21.1b-41b": {
|
||||
"input_cost_per_token": 0.0000008,
|
||||
"output_cost_per_token": 0.0000008,
|
||||
"litellm_provider": "together_ai"
|
||||
},
|
||||
"together-ai-40.1b-70b": {
|
||||
"together-ai-41.1b-80b": {
|
||||
"input_cost_per_token": 0.0000009,
|
||||
"output_cost_per_token": 0.0000009,
|
||||
"litellm_provider": "together_ai"
|
||||
},
|
||||
"together-ai-81.1b-110b": {
|
||||
"input_cost_per_token": 0.0000018,
|
||||
"output_cost_per_token": 0.0000018,
|
||||
"litellm_provider": "together_ai"
|
||||
},
|
||||
"together_ai/mistralai/Mixtral-8x7B-Instruct-v0.1": {
|
||||
"input_cost_per_token": 0.0000006,
|
||||
"output_cost_per_token": 0.0000006,
|
||||
|
|
|
|||