Merge remote-tracking branch 'origin/main' into fix-sap-creds
 Vasilisa Parshikova
|
|
@ -178,6 +178,7 @@ jobs:
|
|||
pip install "Pillow==10.3.0"
|
||||
pip install "jsonschema==4.22.0"
|
||||
pip install "pytest-xdist==3.6.1"
|
||||
pip install "pytest-timeout==2.2.0"
|
||||
pip install "websockets==13.1.0"
|
||||
pip install semantic_router --no-deps
|
||||
pip install aurelio_sdk --no-deps
|
||||
|
|
@ -208,7 +209,10 @@ jobs:
|
|||
command: |
|
||||
pwd
|
||||
ls
|
||||
python -m pytest -vv tests/local_testing --cov=litellm --cov-report=xml --junitxml=test-results/junit.xml --durations=5 -k "not test_python_38.py and not test_basic_python_version.py and not router and not assistants and not langfuse and not caching and not cache" -n 4
|
||||
# Add --timeout to kill hanging tests after 300s (5 min)
|
||||
# Add -v to show test names as they run for debugging
|
||||
# Add --tb=short for shorter tracebacks
|
||||
python -m pytest -vv tests/local_testing --cov=litellm --cov-report=xml --junitxml=test-results/junit.xml --durations=20 -k "not test_python_38.py and not test_basic_python_version.py and not router and not assistants and not langfuse and not caching and not cache" -n 4 --timeout=300 --timeout_method=thread
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
|
|
@ -614,6 +618,12 @@ jobs:
|
|||
- run:
|
||||
name: Install Dependencies
|
||||
command: |
|
||||
export PATH="$HOME/miniconda/bin:$PATH"
|
||||
source $HOME/miniconda/etc/profile.d/conda.sh
|
||||
conda activate myenv
|
||||
python --version
|
||||
which python
|
||||
pip install --upgrade typing-extensions>=4.12.0
|
||||
pip install "pytest==7.3.1"
|
||||
pip install "pytest-asyncio==0.21.1"
|
||||
pip install aiohttp
|
||||
|
|
@ -677,6 +687,9 @@ jobs:
|
|||
- run:
|
||||
name: Run prisma ./docker/entrypoint.sh
|
||||
command: |
|
||||
export PATH="$HOME/miniconda/bin:$PATH"
|
||||
source $HOME/miniconda/etc/profile.d/conda.sh
|
||||
conda activate myenv
|
||||
set +e
|
||||
chmod +x docker/entrypoint.sh
|
||||
./docker/entrypoint.sh
|
||||
|
|
@ -685,6 +698,9 @@ jobs:
|
|||
- run:
|
||||
name: Run tests
|
||||
command: |
|
||||
export PATH="$HOME/miniconda/bin:$PATH"
|
||||
source $HOME/miniconda/etc/profile.d/conda.sh
|
||||
conda activate myenv
|
||||
pwd
|
||||
ls
|
||||
python -m pytest tests/proxy_security_tests --cov=litellm --cov-report=xml -vv -x -v --junitxml=test-results/junit.xml --durations=5
|
||||
|
|
@ -1090,13 +1106,16 @@ jobs:
|
|||
pip install "pytest-asyncio==0.21.1"
|
||||
pip install "respx==0.22.0"
|
||||
pip install "pytest-xdist==3.6.1"
|
||||
pip install "pytest-timeout==2.2.0"
|
||||
# Run pytest and generate JUnit XML report
|
||||
- run:
|
||||
name: Run tests
|
||||
command: |
|
||||
pwd
|
||||
ls
|
||||
python -m pytest -vv tests/llm_translation --cov=litellm --cov-report=xml -v --junitxml=test-results/junit.xml --durations=5 -n 4
|
||||
# Add --timeout to kill hanging tests after 120s (2 min)
|
||||
# Add --durations=20 to show 20 slowest tests for debugging
|
||||
python -m pytest -vv tests/llm_translation --cov=litellm --cov-report=xml -v --junitxml=test-results/junit.xml --durations=20 -n 4 --timeout=120 --timeout_method=thread
|
||||
no_output_timeout: 120m
|
||||
- run:
|
||||
name: Rename the coverage files
|
||||
|
|
@ -3954,4 +3973,4 @@ workflows:
|
|||
- proxy_pass_through_endpoint_tests
|
||||
- check_code_and_doc_quality
|
||||
- publish_proxy_extras
|
||||
- guardrails_testing
|
||||
- guardrails_testing
|
||||
104
.gitguardian.yaml
Normal file
|
|
@ -0,0 +1,104 @@
|
|||
version: 2
|
||||
|
||||
secret:
|
||||
# Exclude files and paths by globbing
|
||||
ignored_paths:
|
||||
- "**/*.whl"
|
||||
- "**/*.pyc"
|
||||
- "**/__pycache__/**"
|
||||
- "**/node_modules/**"
|
||||
- "**/dist/**"
|
||||
- "**/build/**"
|
||||
- "**/.git/**"
|
||||
- "**/venv/**"
|
||||
- "**/.venv/**"
|
||||
|
||||
# Large data/metadata files that don't need scanning
|
||||
- "**/model_prices_and_context_window*.json"
|
||||
- "**/*_metadata/*.txt"
|
||||
- "**/tokenizers/*.json"
|
||||
- "**/tokenizers/*"
|
||||
- "miniconda.sh"
|
||||
|
||||
# Build outputs and static assets
|
||||
- "litellm/proxy/_experimental/out/**"
|
||||
- "ui/litellm-dashboard/public/**"
|
||||
- "**/swagger/*.js"
|
||||
- "**/*.woff"
|
||||
- "**/*.woff2"
|
||||
- "**/*.avif"
|
||||
- "**/*.webp"
|
||||
|
||||
# Test data files
|
||||
- "**/tests/**/data_map.txt"
|
||||
- "tests/**/*.txt"
|
||||
|
||||
# Documentation and other non-code files
|
||||
- "docs/**"
|
||||
- "**/*.md"
|
||||
- "**/*.lock"
|
||||
- "poetry.lock"
|
||||
- "package-lock.json"
|
||||
|
||||
# Ignore security incidents with the SHA256 of the occurrence (false positives)
|
||||
ignored_matches:
|
||||
# === Current detected false positives (SHA-based) ===
|
||||
|
||||
# gcs_pub_sub_body - folder name, not a password
|
||||
- name: GCS pub/sub test folder name
|
||||
match: 75f377c456eede69e5f6e47399ccee6016a2a93cc5dd11db09cc5b1359ae569a
|
||||
|
||||
# os.environ/APORIA_API_KEY_1 - environment variable reference
|
||||
- name: Environment variable reference APORIA_API_KEY_1
|
||||
match: e2ddeb8b88eca97a402559a2be2117764e11c074d86159ef9ad2375dea188094
|
||||
|
||||
# os.environ/APORIA_API_KEY_2 - environment variable reference
|
||||
- name: Environment variable reference APORIA_API_KEY_2
|
||||
match: 09aa39a29e050b86603aa55138af1ff08fb86a4582aa965c1bd0672e1575e052
|
||||
|
||||
# oidc/circleci_v2/ - test authentication path, not a secret
|
||||
- name: OIDC CircleCI test path
|
||||
match: feb3475e1f89a65b7b7815ac4ec597e18a9ec1847742ad445c36ca617b536e15
|
||||
|
||||
# text-davinci-003 - OpenAI model identifier, not a secret
|
||||
- name: OpenAI model identifier text-davinci-003
|
||||
match: c489000cf6c7600cee0eefb80ad0965f82921cfb47ece880930eb7e7635cf1f1
|
||||
|
||||
# Base64 Basic Auth in test_pass_through_endpoints.py - test fixture, not a real secret
|
||||
- name: Test Base64 Basic Auth header in pass_through_endpoints test
|
||||
match: 61bac0491f395040617df7ef6d06029eac4d92a4457ac784978db80d97be1ae0
|
||||
|
||||
# PostgreSQL password "postgres" in CI configs - standard test database password
|
||||
- name: Test PostgreSQL password in CI configurations
|
||||
match: 6e0d657eb1f0fbc40cf0b8f3c3873ef627cc9cb7c4108d1c07d979c04bc8a4bb
|
||||
|
||||
# Bearer token in locustfile.py - test/example API key for load testing
|
||||
- name: Test Bearer token in locustfile load test
|
||||
match: 2a0abc2b0c3c1760a51ffcdf8d6b1d384cef69af740504b1cfa82dd70cdc7ff9
|
||||
|
||||
# Inkeep API key in docusaurus.config.js - public documentation site key
|
||||
- name: Inkeep API key in documentation config
|
||||
match: c366657791bfb5fc69045ec11d49452f09a0aebbc8648f94e2469b4025e29a75
|
||||
|
||||
# Langfuse credentials in test_completion.py - test credentials for integration test
|
||||
- name: Langfuse test credentials in test_completion
|
||||
match: c39310f68cc3d3e22f7b298bb6353c4f45759adcc37080d8b7f4e535d3cfd7f4
|
||||
|
||||
# === Preventive patterns for test keys (pattern-based) ===
|
||||
|
||||
# Test API keys (124 instances across 45 files)
|
||||
- name: Test API keys with sk-test prefix
|
||||
match: sk-test-
|
||||
|
||||
# Mock API keys
|
||||
- name: Mock API keys with sk-mock prefix
|
||||
match: sk-mock-
|
||||
|
||||
# Fake API keys
|
||||
- name: Fake API keys with sk-fake prefix
|
||||
match: sk-fake-
|
||||
|
||||
# Generic test API key patterns
|
||||
- name: Test API key patterns
|
||||
match: test-api-key
|
||||
|
||||
21
AGENTS.md
|
|
@ -49,6 +49,27 @@ LiteLLM is a unified interface for 100+ LLMs that:
|
|||
- Test provider-specific functionality thoroughly
|
||||
- Consider adding load tests for performance-critical changes
|
||||
|
||||
### MAKING CODE CHANGES FOR THE UI (IGNORE FOR BACKEND)
|
||||
|
||||
1. **Use Common Components as much as possible**:
|
||||
- These are usually defined in the `common_components` directory
|
||||
- Use these components as much as possible and avoid building new components unless needed
|
||||
- Tremor components are deprecated; prefer using Ant Design (AntD) as much as possible
|
||||
|
||||
2. **Testing**:
|
||||
- The codebase uses **Vitest** and **React Testing Library**
|
||||
- **Query Priority Order**: Use query methods in this order: `getByRole`, `getByLabelText`, `getByPlaceholderText`, `getByText`, `getByTestId`
|
||||
- **Always use `screen`** instead of destructuring from `render()` (e.g., use `screen.getByText()` not `getByText`)
|
||||
- **Wrap user interactions in `act()`**: Always wrap `fireEvent` calls with `act()` to ensure React state updates are properly handled
|
||||
- **Use `query` methods for absence checks**: Use `queryBy*` methods (not `getBy*`) when expecting an element to NOT be present
|
||||
- **Test names must start with "should"**: All test names should follow the pattern `it("should ...")`
|
||||
- **Mock external dependencies**: Check `setupTests.ts` for global mocks and mock child components/networking calls as needed
|
||||
- **Structure tests properly**:
|
||||
- First test should verify the component renders successfully
|
||||
- Subsequent tests should focus on functionality and user interactions
|
||||
- Use `waitFor` for async operations that aren't already awaited
|
||||
- **Avoid using `querySelector`**: Prefer React Testing Library queries over direct DOM manipulation
|
||||
|
||||
### IMPORTANT PATTERNS
|
||||
|
||||
1. **Function/Tool Calling**:
|
||||
|
|
|
|||
428
README.md
|
|
@ -2,16 +2,16 @@
|
|||
🚅 LiteLLM
|
||||
</h1>
|
||||
<p align="center">
|
||||
<p align="center">Call 100+ LLMs in OpenAI format. [Bedrock, Azure, OpenAI, VertexAI, Anthropic, Groq, etc.]
|
||||
</p>
|
||||
<p align="center">
|
||||
<a href="https://render.com/deploy?repo=https://github.com/BerriAI/litellm" target="_blank" rel="nofollow"><img src="https://render.com/images/deploy-to-render-button.svg" alt="Deploy to Render"></a>
|
||||
<a href="https://railway.app/template/HLP0Ub?referralCode=jch2ME">
|
||||
<img src="https://railway.app/button.svg" alt="Deploy on Railway">
|
||||
</a>
|
||||
</p>
|
||||
<p align="center">Call all LLM APIs using the OpenAI format [Bedrock, Huggingface, VertexAI, TogetherAI, Azure, OpenAI, Groq etc.]
|
||||
<br>
|
||||
</p>
|
||||
<h4 align="center"><a href="https://docs.litellm.ai/docs/simple_proxy" target="_blank">LiteLLM Proxy Server (LLM Gateway)</a> | <a href="https://docs.litellm.ai/docs/enterprise#hosted-litellm-proxy" target="_blank"> Hosted Proxy</a> | <a href="https://docs.litellm.ai/docs/enterprise"target="_blank">Enterprise Tier</a></h4>
|
||||
<h4 align="center"><a href="https://docs.litellm.ai/docs/simple_proxy" target="_blank">LiteLLM Proxy Server (AI Gateway)</a> | <a href="https://docs.litellm.ai/docs/enterprise#hosted-litellm-proxy" target="_blank"> Hosted Proxy</a> | <a href="https://docs.litellm.ai/docs/enterprise"target="_blank">Enterprise Tier</a></h4>
|
||||
<h4 align="center">
|
||||
<a href="https://pypi.org/project/litellm/" target="_blank">
|
||||
<img src="https://img.shields.io/pypi/v/litellm.svg" alt="PyPI Version">
|
||||
|
|
@ -30,27 +30,17 @@
|
|||
</a>
|
||||
</h4>
|
||||
|
||||
LiteLLM manages:
|
||||
<img width="2688" height="1600" alt="Group 7154 (1)" src="https://github.com/user-attachments/assets/c5ee0412-6fb5-4fb6-ab5b-bafae4209ca6" />
|
||||
|
||||
- Translate inputs to provider's `completion`, `embedding`, and `image_generation` endpoints
|
||||
- [Consistent output](https://docs.litellm.ai/docs/completion/output), text responses will always be available at `['choices'][0]['message']['content']`
|
||||
- Retry/fallback logic across multiple deployments (e.g. Azure/OpenAI) - [Router](https://docs.litellm.ai/docs/routing)
|
||||
- Set Budgets & Rate limits per project, api key, model [LiteLLM Proxy Server (LLM Gateway)](https://docs.litellm.ai/docs/simple_proxy)
|
||||
|
||||
LiteLLM Performance: **8ms P95 latency** at 1k RPS (See benchmarks [here](https://docs.litellm.ai/docs/benchmarks))
|
||||
## Use LiteLLM for
|
||||
|
||||
[**Jump to LiteLLM Proxy (LLM Gateway) Docs**](https://github.com/BerriAI/litellm?tab=readme-ov-file#litellm-proxy-server-llm-gateway---docs) <br>
|
||||
[**Jump to Supported LLM Providers**](https://docs.litellm.ai/docs/providers)
|
||||
<details open>
|
||||
<summary><b>LLMs</b> - Call 100+ LLMs (Python SDK + AI Gateway)</summary>
|
||||
|
||||
🚨 **Stable Release:** Use docker images with the `-stable` tag. These have undergone 12 hour load tests, before being published. [More information about the release cycle here](https://docs.litellm.ai/docs/proxy/release_cycle)
|
||||
[**All Supported Endpoints**](https://docs.litellm.ai/docs/supported_endpoints) - `/chat/completions`, `/responses`, `/embeddings`, `/images`, `/audio`, `/batches`, `/rerank`, `/a2a`, `/messages` and more.
|
||||
|
||||
Support for more providers. Missing a provider or LLM Platform, raise a [feature request](https://github.com/BerriAI/litellm/issues/new?assignees=&labels=enhancement&projects=&template=feature_request.yml&title=%5BFeature%5D%3A+).
|
||||
|
||||
# Usage ([**Docs**](https://docs.litellm.ai/docs/))
|
||||
|
||||
<a target="_blank" href="https://colab.research.google.com/github/BerriAI/litellm/blob/main/cookbook/liteLLM_Getting_Started.ipynb">
|
||||
<img src="https://colab.research.google.com/assets/colab-badge.svg" alt="Open In Colab"/>
|
||||
</a>
|
||||
### Python SDK
|
||||
|
||||
```shell
|
||||
pip install litellm
|
||||
|
|
@ -60,249 +50,214 @@ pip install litellm
|
|||
from litellm import completion
|
||||
import os
|
||||
|
||||
## set ENV variables
|
||||
os.environ["OPENAI_API_KEY"] = "your-openai-key"
|
||||
os.environ["ANTHROPIC_API_KEY"] = "your-anthropic-key"
|
||||
|
||||
messages = [{ "content": "Hello, how are you?","role": "user"}]
|
||||
# OpenAI
|
||||
response = completion(model="openai/gpt-4o", messages=[{"role": "user", "content": "Hello!"}])
|
||||
|
||||
# openai call
|
||||
response = completion(model="openai/gpt-4o", messages=messages)
|
||||
|
||||
# anthropic call
|
||||
response = completion(model="anthropic/claude-sonnet-4-20250514", messages=messages)
|
||||
print(response)
|
||||
# Anthropic
|
||||
response = completion(model="anthropic/claude-sonnet-4-20250514", messages=[{"role": "user", "content": "Hello!"}])
|
||||
```
|
||||
|
||||
### Response (OpenAI Format)
|
||||
### AI Gateway (Proxy Server)
|
||||
|
||||
```json
|
||||
{
|
||||
"id": "chatcmpl-1214900a-6cdd-4148-b663-b5e2f642b4de",
|
||||
"created": 1751494488,
|
||||
"model": "claude-sonnet-4-20250514",
|
||||
"object": "chat.completion",
|
||||
"system_fingerprint": null,
|
||||
"choices": [
|
||||
{
|
||||
"finish_reason": "stop",
|
||||
"index": 0,
|
||||
"message": {
|
||||
"content": "Hello! I'm doing well, thank you for asking. I'm here and ready to help with whatever you'd like to discuss or work on. How are you doing today?",
|
||||
"role": "assistant",
|
||||
"tool_calls": null,
|
||||
"function_call": null
|
||||
}
|
||||
}
|
||||
],
|
||||
"usage": {
|
||||
"completion_tokens": 39,
|
||||
"prompt_tokens": 13,
|
||||
"total_tokens": 52,
|
||||
"completion_tokens_details": null,
|
||||
"prompt_tokens_details": {
|
||||
"audio_tokens": null,
|
||||
"cached_tokens": 0
|
||||
},
|
||||
"cache_creation_input_tokens": 0,
|
||||
"cache_read_input_tokens": 0
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
> **Note:** LiteLLM also supports the [Responses API](https://docs.litellm.ai/docs/response_api) (`litellm.responses()`)
|
||||
|
||||
Call any model supported by a provider, with `model=<provider_name>/<model_name>`. There might be provider-specific details here, so refer to [provider docs for more information](https://docs.litellm.ai/docs/providers)
|
||||
|
||||
## Async ([Docs](https://docs.litellm.ai/docs/completion/stream#async-completion))
|
||||
|
||||
```python
|
||||
from litellm import acompletion
|
||||
import asyncio
|
||||
|
||||
async def test_get_response():
|
||||
user_message = "Hello, how are you?"
|
||||
messages = [{"content": user_message, "role": "user"}]
|
||||
response = await acompletion(model="openai/gpt-4o", messages=messages)
|
||||
return response
|
||||
|
||||
response = asyncio.run(test_get_response())
|
||||
print(response)
|
||||
```
|
||||
|
||||
## Streaming ([Docs](https://docs.litellm.ai/docs/completion/stream))
|
||||
|
||||
LiteLLM supports streaming the model response back, pass `stream=True` to get a streaming iterator in response.
|
||||
Streaming is supported for all models (Bedrock, Huggingface, TogetherAI, Azure, OpenAI, etc.)
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
messages = [{"content": "Hello, how are you?", "role": "user"}]
|
||||
|
||||
# gpt-4o
|
||||
response = completion(model="openai/gpt-4o", messages=messages, stream=True)
|
||||
for part in response:
|
||||
print(part.choices[0].delta.content or "")
|
||||
|
||||
# claude sonnet 4
|
||||
response = completion('anthropic/claude-sonnet-4-20250514', messages, stream=True)
|
||||
for part in response:
|
||||
print(part)
|
||||
```
|
||||
|
||||
### Response chunk (OpenAI Format)
|
||||
|
||||
```json
|
||||
{
|
||||
"id": "chatcmpl-fe575c37-5004-4926-ae5e-bfbc31f356ca",
|
||||
"created": 1751494808,
|
||||
"model": "claude-sonnet-4-20250514",
|
||||
"object": "chat.completion.chunk",
|
||||
"system_fingerprint": null,
|
||||
"choices": [
|
||||
{
|
||||
"finish_reason": null,
|
||||
"index": 0,
|
||||
"delta": {
|
||||
"provider_specific_fields": null,
|
||||
"content": "Hello",
|
||||
"role": "assistant",
|
||||
"function_call": null,
|
||||
"tool_calls": null,
|
||||
"audio": null
|
||||
},
|
||||
"logprobs": null
|
||||
}
|
||||
],
|
||||
"provider_specific_fields": null,
|
||||
"stream_options": null,
|
||||
"citations": null
|
||||
}
|
||||
```
|
||||
|
||||
## Logging Observability ([Docs](https://docs.litellm.ai/docs/observability/callbacks))
|
||||
|
||||
LiteLLM exposes pre defined callbacks to send data to Lunary, MLflow, Langfuse, DynamoDB, s3 Buckets, Helicone, Promptlayer, Traceloop, Athina, Slack
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
## set env variables for logging tools (when using MLflow, no API key set up is required)
|
||||
os.environ["LUNARY_PUBLIC_KEY"] = "your-lunary-public-key"
|
||||
os.environ["HELICONE_API_KEY"] = "your-helicone-auth-key"
|
||||
os.environ["LANGFUSE_PUBLIC_KEY"] = ""
|
||||
os.environ["LANGFUSE_SECRET_KEY"] = ""
|
||||
os.environ["ATHINA_API_KEY"] = "your-athina-api-key"
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "your-openai-key"
|
||||
|
||||
# set callbacks
|
||||
litellm.success_callback = ["lunary", "mlflow", "langfuse", "athina", "helicone"] # log input/output to lunary, langfuse, supabase, athina, helicone etc
|
||||
|
||||
#openai call
|
||||
response = completion(model="openai/gpt-4o", messages=[{"role": "user", "content": "Hi 👋 - i'm openai"}])
|
||||
```
|
||||
|
||||
# LiteLLM Proxy Server (LLM Gateway) - ([Docs](https://docs.litellm.ai/docs/simple_proxy))
|
||||
|
||||
Track spend + Load Balance across multiple projects
|
||||
|
||||
[Hosted Proxy](https://docs.litellm.ai/docs/enterprise#hosted-litellm-proxy)
|
||||
|
||||
The proxy provides:
|
||||
|
||||
1. [Hooks for auth](https://docs.litellm.ai/docs/proxy/virtual_keys#custom-auth)
|
||||
2. [Hooks for logging](https://docs.litellm.ai/docs/proxy/logging#step-1---create-your-custom-litellm-callback-class)
|
||||
3. [Cost tracking](https://docs.litellm.ai/docs/proxy/virtual_keys#tracking-spend)
|
||||
4. [Rate Limiting](https://docs.litellm.ai/docs/proxy/users#set-rate-limits)
|
||||
|
||||
## 📖 Proxy Endpoints - [Swagger Docs](https://litellm-api.up.railway.app/)
|
||||
|
||||
|
||||
## Quick Start Proxy - CLI
|
||||
[**Getting Started - E2E Tutorial**](https://docs.litellm.ai/docs/proxy/docker_quick_start) - Setup virtual keys, make your first request
|
||||
|
||||
```shell
|
||||
pip install 'litellm[proxy]'
|
||||
litellm --model gpt-4o
|
||||
```
|
||||
|
||||
### Step 1: Start litellm proxy
|
||||
|
||||
```shell
|
||||
$ litellm --model huggingface/bigcode/starcoder
|
||||
|
||||
#INFO: Proxy running on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
### Step 2: Make ChatCompletions Request to Proxy
|
||||
|
||||
|
||||
> [!IMPORTANT]
|
||||
> 💡 [Use LiteLLM Proxy with Langchain (Python, JS), OpenAI SDK (Python, JS) Anthropic SDK, Mistral SDK, LlamaIndex, Instructor, Curl](https://docs.litellm.ai/docs/proxy/user_keys)
|
||||
|
||||
```python
|
||||
import openai # openai v1.0.0+
|
||||
client = openai.OpenAI(api_key="anything",base_url="http://0.0.0.0:4000") # set proxy to base_url
|
||||
# request sent to model set on litellm proxy, `litellm --model`
|
||||
response = client.chat.completions.create(model="gpt-3.5-turbo", messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "this is a test request, write a short poem"
|
||||
}
|
||||
])
|
||||
import openai
|
||||
|
||||
print(response)
|
||||
client = openai.OpenAI(api_key="anything", base_url="http://0.0.0.0:4000")
|
||||
response = client.chat.completions.create(
|
||||
model="gpt-4o",
|
||||
messages=[{"role": "user", "content": "Hello!"}]
|
||||
)
|
||||
```
|
||||
|
||||
## Proxy Key Management ([Docs](https://docs.litellm.ai/docs/proxy/virtual_keys))
|
||||
[**Docs: LLM Providers**](https://docs.litellm.ai/docs/providers)
|
||||
|
||||
Connect the proxy with a Postgres DB to create proxy keys
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Agents</b> - Invoke A2A Agents (Python SDK + AI Gateway)</summary>
|
||||
|
||||
[**Supported Providers**](https://docs.litellm.ai/docs/a2a#add-a2a-agents) - LangGraph, Vertex AI Agent Engine, Azure AI Foundry, Bedrock AgentCore, Pydantic AI
|
||||
|
||||
### Python SDK - A2A Protocol
|
||||
|
||||
```python
|
||||
from litellm.a2a_protocol import A2AClient
|
||||
from a2a.types import SendMessageRequest, MessageSendParams
|
||||
from uuid import uuid4
|
||||
|
||||
client = A2AClient(base_url="http://localhost:10001")
|
||||
|
||||
request = SendMessageRequest(
|
||||
id=str(uuid4()),
|
||||
params=MessageSendParams(
|
||||
message={
|
||||
"role": "user",
|
||||
"parts": [{"kind": "text", "text": "Hello!"}],
|
||||
"messageId": uuid4().hex,
|
||||
}
|
||||
)
|
||||
)
|
||||
response = await client.send_message(request)
|
||||
```
|
||||
|
||||
### AI Gateway (Proxy Server)
|
||||
|
||||
**Step 1.** [Add your Agent to the AI Gateway](https://docs.litellm.ai/docs/a2a#adding-your-agent)
|
||||
|
||||
**Step 2.** Call Agent via A2A SDK
|
||||
|
||||
```python
|
||||
from a2a.client import A2ACardResolver, A2AClient
|
||||
from a2a.types import MessageSendParams, SendMessageRequest
|
||||
from uuid import uuid4
|
||||
import httpx
|
||||
|
||||
base_url = "http://localhost:4000/a2a/my-agent" # LiteLLM proxy + agent name
|
||||
headers = {"Authorization": "Bearer sk-1234"} # LiteLLM Virtual Key
|
||||
|
||||
async with httpx.AsyncClient(headers=headers) as httpx_client:
|
||||
resolver = A2ACardResolver(httpx_client=httpx_client, base_url=base_url)
|
||||
agent_card = await resolver.get_agent_card()
|
||||
client = A2AClient(httpx_client=httpx_client, agent_card=agent_card)
|
||||
|
||||
request = SendMessageRequest(
|
||||
id=str(uuid4()),
|
||||
params=MessageSendParams(
|
||||
message={
|
||||
"role": "user",
|
||||
"parts": [{"kind": "text", "text": "Hello!"}],
|
||||
"messageId": uuid4().hex,
|
||||
}
|
||||
)
|
||||
)
|
||||
response = await client.send_message(request)
|
||||
```
|
||||
|
||||
[**Docs: A2A Agent Gateway**](https://docs.litellm.ai/docs/a2a)
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>MCP Tools</b> - Connect MCP servers to any LLM (Python SDK + AI Gateway)</summary>
|
||||
|
||||
### Python SDK - MCP Bridge
|
||||
|
||||
```python
|
||||
from mcp import ClientSession, StdioServerParameters
|
||||
from mcp.client.stdio import stdio_client
|
||||
from litellm import experimental_mcp_client
|
||||
import litellm
|
||||
|
||||
server_params = StdioServerParameters(command="python", args=["mcp_server.py"])
|
||||
|
||||
async with stdio_client(server_params) as (read, write):
|
||||
async with ClientSession(read, write) as session:
|
||||
await session.initialize()
|
||||
|
||||
# Load MCP tools in OpenAI format
|
||||
tools = await experimental_mcp_client.load_mcp_tools(session=session, format="openai")
|
||||
|
||||
# Use with any LiteLLM model
|
||||
response = await litellm.acompletion(
|
||||
model="gpt-4o",
|
||||
messages=[{"role": "user", "content": "What's 3 + 5?"}],
|
||||
tools=tools
|
||||
)
|
||||
```
|
||||
|
||||
### AI Gateway - MCP Gateway
|
||||
|
||||
**Step 1.** [Add your MCP Server to the AI Gateway](https://docs.litellm.ai/docs/mcp#adding-your-mcp)
|
||||
|
||||
**Step 2.** Call MCP tools via `/chat/completions`
|
||||
|
||||
```bash
|
||||
# Get the code
|
||||
git clone https://github.com/BerriAI/litellm
|
||||
|
||||
# Go to folder
|
||||
cd litellm
|
||||
|
||||
# Add the master key - you can change this after setup
|
||||
echo 'LITELLM_MASTER_KEY="sk-1234"' > .env
|
||||
|
||||
# Add the litellm salt key - you cannot change this after adding a model
|
||||
# It is used to encrypt / decrypt your LLM API Key credentials
|
||||
# We recommend - https://1password.com/password-generator/
|
||||
# password generator to get a random hash for litellm salt key
|
||||
echo 'LITELLM_SALT_KEY="sk-1234"' >> .env
|
||||
|
||||
# Start
|
||||
docker compose up
|
||||
curl -X POST 'http://0.0.0.0:4000/v1/chat/completions' \
|
||||
-H 'Authorization: Bearer sk-1234' \
|
||||
-H 'Content-Type: application/json' \
|
||||
-d '{
|
||||
"model": "gpt-4o",
|
||||
"messages": [{"role": "user", "content": "Summarize the latest open PR"}],
|
||||
"tools": [{
|
||||
"type": "mcp",
|
||||
"server_url": "litellm_proxy/mcp/github",
|
||||
"server_label": "github_mcp",
|
||||
"require_approval": "never"
|
||||
}]
|
||||
}'
|
||||
```
|
||||
|
||||
### Use with Cursor IDE
|
||||
|
||||
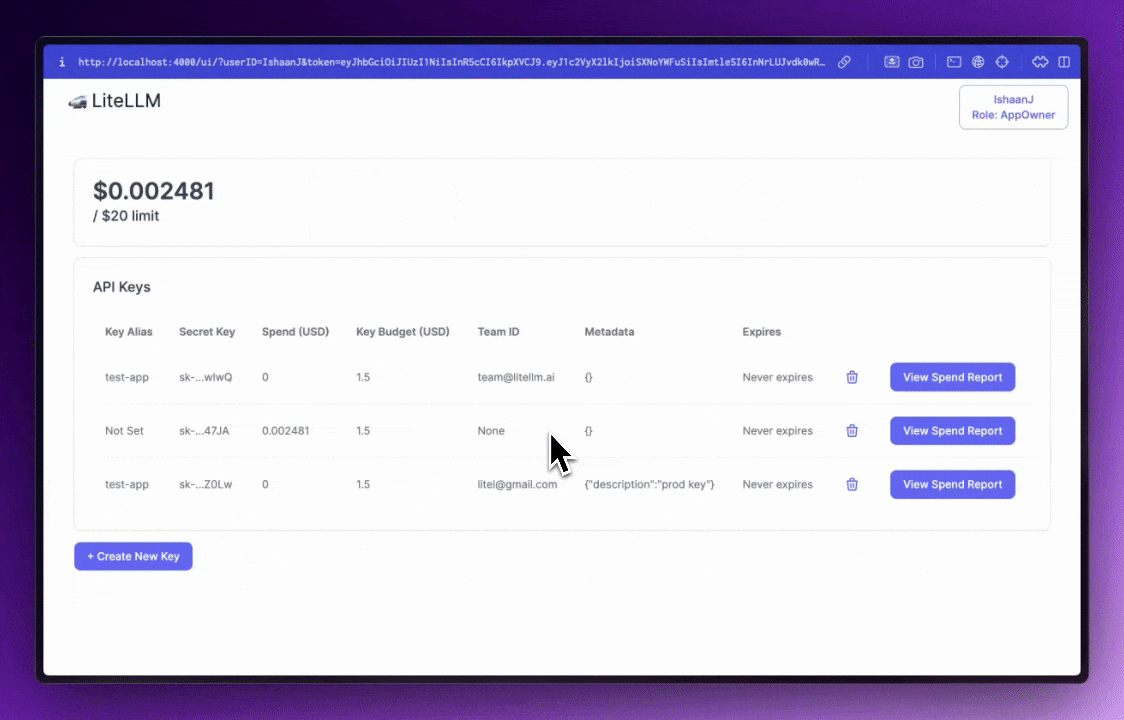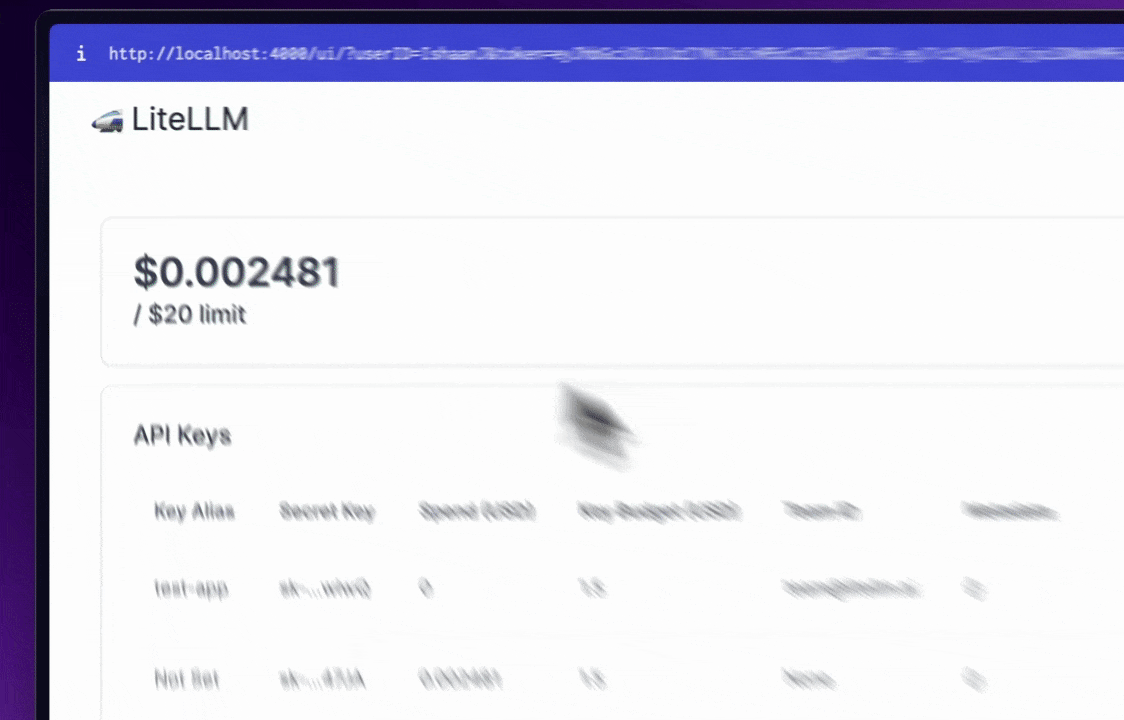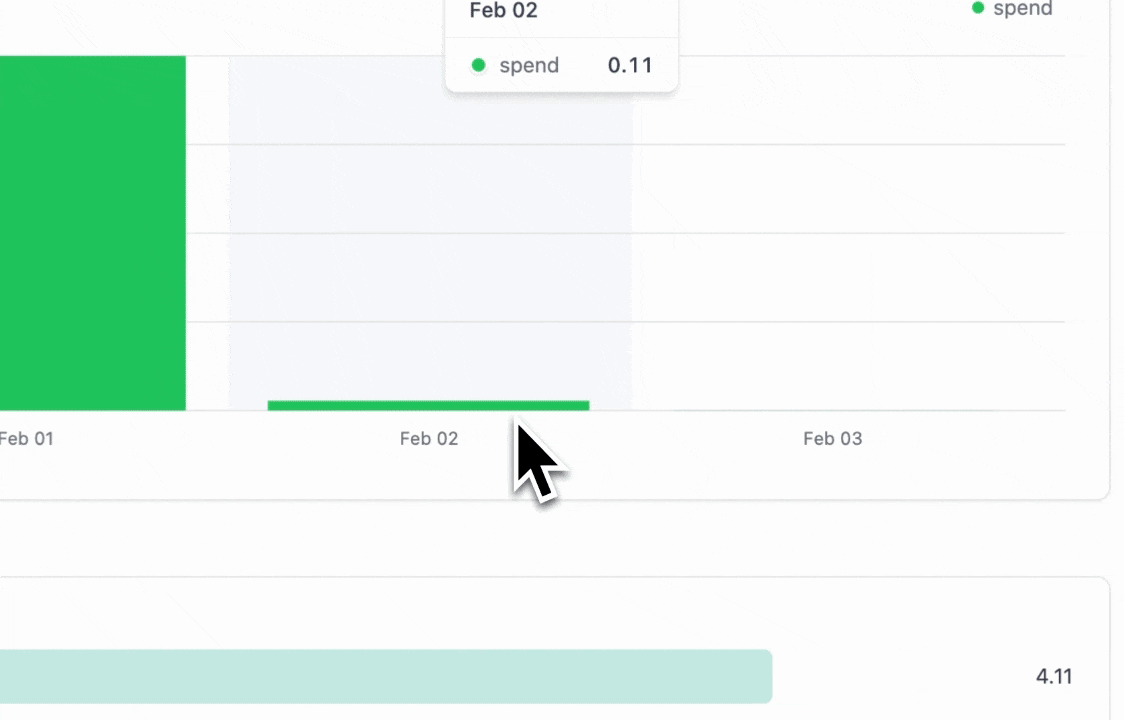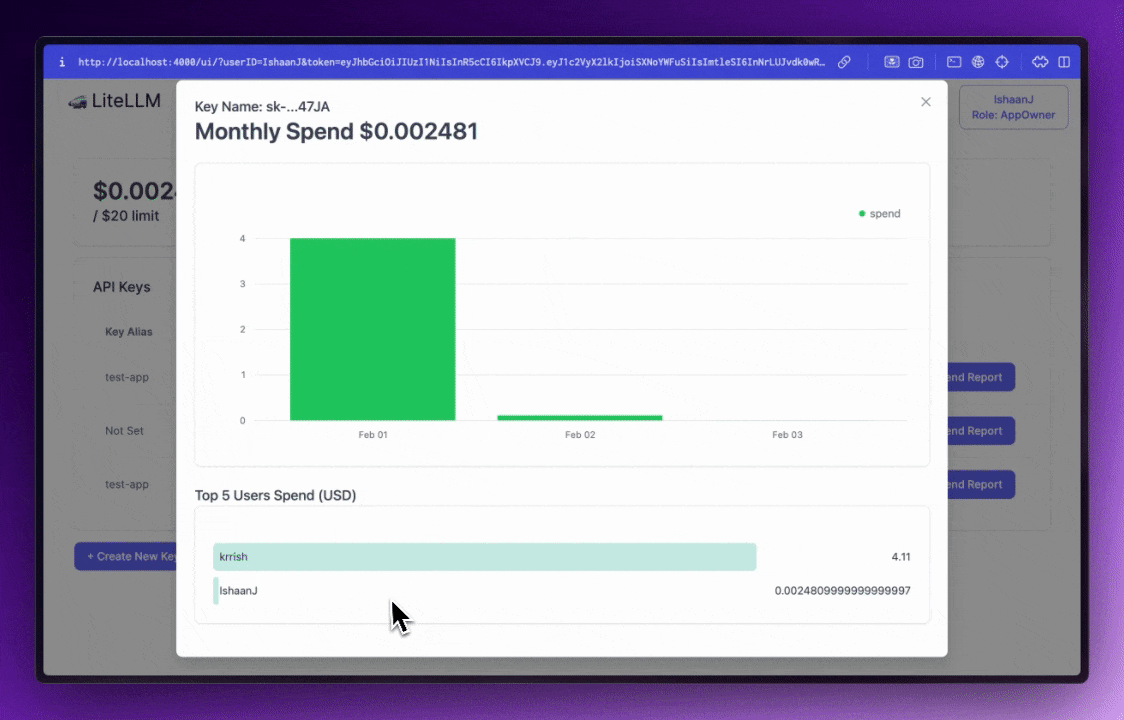
UI on `/ui` on your proxy server
|
||||
|
||||
|
||||
Set budgets and rate limits across multiple projects
|
||||
`POST /key/generate`
|
||||
|
||||
### Request
|
||||
|
||||
```shell
|
||||
curl 'http://0.0.0.0:4000/key/generate' \
|
||||
--header 'Authorization: Bearer sk-1234' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data-raw '{"models": ["gpt-3.5-turbo", "gpt-4", "claude-2"], "duration": "20m","metadata": {"user": "ishaan@berri.ai", "team": "core-infra"}}'
|
||||
```
|
||||
|
||||
### Expected Response
|
||||
|
||||
```shell
|
||||
```json
|
||||
{
|
||||
"key": "sk-kdEXbIqZRwEeEiHwdg7sFA", # Bearer token
|
||||
"expires": "2023-11-19T01:38:25.838000+00:00" # datetime object
|
||||
"mcpServers": {
|
||||
"LiteLLM": {
|
||||
"url": "http://localhost:4000/mcp",
|
||||
"headers": {
|
||||
"x-litellm-api-key": "Bearer sk-1234"
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
[**Docs: MCP Gateway**](https://docs.litellm.ai/docs/mcp)
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## How to use LiteLLM
|
||||
|
||||
You can use LiteLLM through either the Proxy Server or Python SDK. Both gives you a unified interface to access multiple LLMs (100+ LLMs). Choose the option that best fits your needs:
|
||||
|
||||
<table style={{width: '100%', tableLayout: 'fixed'}}>
|
||||
<thead>
|
||||
<tr>
|
||||
<th style={{width: '14%'}}></th>
|
||||
<th style={{width: '43%'}}><strong><a href="https://docs.litellm.ai/docs/simple_proxy">LiteLLM AI Gateway</a></strong></th>
|
||||
<th style={{width: '43%'}}><strong><a href="https://docs.litellm.ai/docs/">LiteLLM Python SDK</a></strong></th>
|
||||
</tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
<tr>
|
||||
<td style={{width: '14%'}}><strong>Use Case</strong></td>
|
||||
<td style={{width: '43%'}}>Central service (LLM Gateway) to access multiple LLMs</td>
|
||||
<td style={{width: '43%'}}>Use LiteLLM directly in your Python code</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td style={{width: '14%'}}><strong>Who Uses It?</strong></td>
|
||||
<td style={{width: '43%'}}>Gen AI Enablement / ML Platform Teams</td>
|
||||
<td style={{width: '43%'}}>Developers building LLM projects</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td style={{width: '14%'}}><strong>Key Features</strong></td>
|
||||
<td style={{width: '43%'}}>Centralized API gateway with authentication and authorization, multi-tenant cost tracking and spend management per project/user, per-project customization (logging, guardrails, caching), virtual keys for secure access control, admin dashboard UI for monitoring and management</td>
|
||||
<td style={{width: '43%'}}>Direct Python library integration in your codebase, Router with retry/fallback logic across multiple deployments (e.g. Azure/OpenAI) - <a href="https://docs.litellm.ai/docs/routing">Router</a>, application-level load balancing and cost tracking, exception handling with OpenAI-compatible errors, observability callbacks (Lunary, MLflow, Langfuse, etc.)</td>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
|
||||
LiteLLM Performance: **8ms P95 latency** at 1k RPS (See benchmarks [here](https://docs.litellm.ai/docs/benchmarks))
|
||||
|
||||
[**Jump to LiteLLM Proxy (LLM Gateway) Docs**](https://docs.litellm.ai/docs/simple_proxy) <br>
|
||||
[**Jump to Supported LLM Providers**](https://docs.litellm.ai/docs/providers)
|
||||
|
||||
**Stable Release:** Use docker images with the `-stable` tag. These have undergone 12 hour load tests, before being published. [More information about the release cycle here](https://docs.litellm.ai/docs/proxy/release_cycle)
|
||||
|
||||
Support for more providers. Missing a provider or LLM Platform, raise a [feature request](https://github.com/BerriAI/litellm/issues/new?assignees=&labels=enhancement&projects=&template=feature_request.yml&title=%5BFeature%5D%3A+).
|
||||
|
||||
## Supported Providers ([Website Supported Models](https://models.litellm.ai/) | [Docs](https://docs.litellm.ai/docs/providers))
|
||||
|
||||
| Provider | `/chat/completions` | `/messages` | `/responses` | `/embeddings` | `/image/generations` | `/audio/transcriptions` | `/audio/speech` | `/moderations` | `/batches` | `/rerank` |
|
||||
|
|
@ -311,6 +266,7 @@ curl 'http://0.0.0.0:4000/key/generate' \
|
|||
| [AI21 (`ai21`)](https://docs.litellm.ai/docs/providers/ai21) | ✅ | ✅ | ✅ | | | | | | | |
|
||||
| [AI21 Chat (`ai21_chat`)](https://docs.litellm.ai/docs/providers/ai21) | ✅ | ✅ | ✅ | | | | | | | |
|
||||
| [Aleph Alpha](https://docs.litellm.ai/docs/providers/aleph_alpha) | ✅ | ✅ | ✅ | | | | | | | |
|
||||
| [Amazon Nova](https://docs.litellm.ai/docs/providers/amazon_nova) | ✅ | ✅ | ✅ | | | | | | | |
|
||||
| [Anthropic (`anthropic`)](https://docs.litellm.ai/docs/providers/anthropic) | ✅ | ✅ | ✅ | | | | | | ✅ | |
|
||||
| [Anthropic Text (`anthropic_text`)](https://docs.litellm.ai/docs/providers/anthropic) | ✅ | ✅ | ✅ | | | | | | ✅ | |
|
||||
| [Anyscale](https://docs.litellm.ai/docs/providers/anyscale) | ✅ | ✅ | ✅ | | | | | | | |
|
||||
|
|
|
|||
40
ci_cd/TEST_KEY_PATTERNS.md
Normal file
|
|
@ -0,0 +1,40 @@
|
|||
# Test Key Patterns Standard
|
||||
|
||||
Standard patterns for test/mock keys and credentials in the LiteLLM codebase to avoid triggering secret detection.
|
||||
|
||||
## How GitGuardian Works
|
||||
|
||||
GitGuardian uses **machine learning and entropy analysis**, not just pattern matching:
|
||||
- **Low entropy** values (like `sk-1234`, `postgres`) are automatically ignored
|
||||
- **High entropy** values (realistic-looking secrets) trigger detection
|
||||
- **Context-aware** detection understands code syntax like `os.environ["KEY"]`
|
||||
|
||||
## Recommended Test Key Patterns
|
||||
|
||||
### Option 1: Low Entropy Values (Simplest)
|
||||
These won't trigger GitGuardian's ML detector:
|
||||
|
||||
```python
|
||||
api_key = "sk-1234"
|
||||
api_key = "sk-12345"
|
||||
database_password = "postgres"
|
||||
token = "test123"
|
||||
```
|
||||
|
||||
### Option 2: High Entropy with Test Prefixes
|
||||
If you need realistic-looking test keys with high entropy, use these prefixes:
|
||||
|
||||
```python
|
||||
api_key = "sk-test-abc123def456ghi789..." # OpenAI-style test key
|
||||
api_key = "sk-mock-1234567890abcdef1234..." # Mock key
|
||||
api_key = "sk-fake-xyz789uvw456rst123..." # Fake key
|
||||
token = "test-api-key-with-high-entropy"
|
||||
```
|
||||
|
||||
## Configured Ignore Patterns
|
||||
|
||||
These patterns are in `.gitguardian.yaml` for high-entropy test keys:
|
||||
- `sk-test-*` - OpenAI-style test keys
|
||||
- `sk-mock-*` - Mock API keys
|
||||
- `sk-fake-*` - Fake API keys
|
||||
- `test-api-key` - Generic test tokens
|
||||
|
|
@ -26,6 +26,56 @@ install_grype() {
|
|||
echo "Grype installed successfully"
|
||||
}
|
||||
|
||||
# Function to install ggshield
|
||||
install_ggshield() {
|
||||
echo "Installing ggshield..."
|
||||
pip3 install --upgrade pip
|
||||
pip3 install ggshield
|
||||
echo "ggshield installed successfully"
|
||||
}
|
||||
|
||||
# Function to run secret detection scans
|
||||
run_secret_detection() {
|
||||
echo "Running secret detection scans..."
|
||||
|
||||
if ! command -v ggshield &> /dev/null; then
|
||||
install_ggshield
|
||||
fi
|
||||
|
||||
# Check if GITGUARDIAN_API_KEY is set (required for CI/CD)
|
||||
if [ -z "$GITGUARDIAN_API_KEY" ]; then
|
||||
echo "Warning: GITGUARDIAN_API_KEY environment variable is not set."
|
||||
echo "ggshield requires a GitGuardian API key to scan for secrets."
|
||||
echo "Please set GITGUARDIAN_API_KEY in your CI/CD environment variables."
|
||||
exit 1
|
||||
fi
|
||||
|
||||
echo "Scanning codebase for secrets..."
|
||||
echo "Note: Large codebases may take several minutes due to API rate limits (50 requests/minute on free plan)"
|
||||
echo "ggshield will automatically handle rate limits and retry as needed."
|
||||
echo "Binary files, cache files, and build artifacts are excluded via .gitguardian.yaml"
|
||||
|
||||
# Use --recursive for directory scanning and auto-confirm if prompted
|
||||
# .gitguardian.yaml will automatically exclude binary files, wheel files, etc.
|
||||
# GITGUARDIAN_API_KEY environment variable will be used for authentication
|
||||
echo y | ggshield secret scan path . --recursive || {
|
||||
echo ""
|
||||
echo "=========================================="
|
||||
echo "ERROR: Secret Detection Failed"
|
||||
echo "=========================================="
|
||||
echo "ggshield has detected secrets in the codebase."
|
||||
echo "Please review discovered secrets above, revoke any actively used secrets"
|
||||
echo "from underlying systems and make changes to inject secrets dynamically at runtime."
|
||||
echo ""
|
||||
echo "For more information, see: https://docs.gitguardian.com/secrets-detection/"
|
||||
echo "=========================================="
|
||||
echo ""
|
||||
exit 1
|
||||
}
|
||||
|
||||
echo "Secret detection scans completed successfully"
|
||||
}
|
||||
|
||||
# Function to run Trivy scans
|
||||
run_trivy_scans() {
|
||||
echo "Running Trivy scans..."
|
||||
|
|
@ -158,6 +208,9 @@ main() {
|
|||
install_trivy
|
||||
install_grype
|
||||
|
||||
echo "Running secret detection scans..."
|
||||
run_secret_detection
|
||||
|
||||
echo "Running filesystem vulnerability scans..."
|
||||
run_trivy_scans
|
||||
|
||||
|
|
|
|||
2
cookbook/LiteLLM_PromptLayer.ipynb
vendored
|
|
@ -39,7 +39,7 @@
|
|||
"import os\n",
|
||||
"os.environ['OPENAI_API_KEY'] = \"\"\n",
|
||||
"os.environ['REPLICATE_API_TOKEN'] = \"\"\n",
|
||||
"os.environ['PROMPTLAYER_API_KEY'] = \"pl_4ea2bb00a4dca1b8a70cebf2e9e11564\"\n",
|
||||
"os.environ['PROMPTLAYER_API_KEY'] = \"test-promptlayer-key-123\"\n",
|
||||
"\n",
|
||||
"# Set Promptlayer as a success callback\n",
|
||||
"litellm.success_callback =['promptlayer']\n",
|
||||
|
|
|
|||
|
|
@ -1,21 +1,10 @@
|
|||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"provenance": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
},
|
||||
"language_info": {
|
||||
"name": "python"
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "kccfk0mHZ4Ad"
|
||||
},
|
||||
"source": [
|
||||
"# Migrating to LiteLLM Proxy from OpenAI/Azure OpenAI\n",
|
||||
"\n",
|
||||
|
|
@ -32,29 +21,26 @@
|
|||
"To pass provider-specific args, [go here](https://docs.litellm.ai/docs/completion/provider_specific_params#proxy-usage)\n",
|
||||
"\n",
|
||||
"To drop unsupported params (E.g. frequency_penalty for bedrock with librechat), [go here](https://docs.litellm.ai/docs/completion/drop_params#openai-proxy-usage)\n"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "kccfk0mHZ4Ad"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "nmSClzCPaGH6"
|
||||
},
|
||||
"source": [
|
||||
"## /chat/completion\n",
|
||||
"\n"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "nmSClzCPaGH6"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"### OpenAI Python SDK"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "_vqcjwOVaKpO"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"### OpenAI Python SDK"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
|
|
@ -94,15 +80,20 @@
|
|||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"## Function Calling"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "AqkyKk9Scxgj"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"## Function Calling"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "wDg10VqLczE1"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from openai import OpenAI\n",
|
||||
"client = OpenAI(\n",
|
||||
|
|
@ -139,24 +130,24 @@
|
|||
")\n",
|
||||
"\n",
|
||||
"print(completion)\n"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "wDg10VqLczE1"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"### Azure OpenAI Python SDK"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "YYoxLloSaNWW"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"### Azure OpenAI Python SDK"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "yA1XcgowaSRy"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import openai\n",
|
||||
"client = openai.AzureOpenAI(\n",
|
||||
|
|
@ -184,24 +175,24 @@
|
|||
")\n",
|
||||
"\n",
|
||||
"print(response)"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "yA1XcgowaSRy"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"### Langchain Python"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "yl9qhDvnaTpL"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"### Langchain Python"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "5MUZgSquaW5t"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from langchain.chat_models import ChatOpenAI\n",
|
||||
"from langchain.prompts.chat import (\n",
|
||||
|
|
@ -239,24 +230,22 @@
|
|||
"response = chat(messages)\n",
|
||||
"\n",
|
||||
"print(response)"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "5MUZgSquaW5t"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"### Curl"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "B9eMgnULbRaz"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"### Curl"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "VWCCk5PFcmhS"
|
||||
},
|
||||
"source": [
|
||||
"\n",
|
||||
"\n",
|
||||
|
|
@ -280,22 +269,24 @@
|
|||
"}'\n",
|
||||
"```\n",
|
||||
"\n"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "VWCCk5PFcmhS"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"### LlamaIndex"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "drBAm2e1b6xe"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"### LlamaIndex"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "d0bZcv8fb9mL"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import os, dotenv\n",
|
||||
"\n",
|
||||
|
|
@ -326,24 +317,24 @@
|
|||
"query_engine = index.as_query_engine()\n",
|
||||
"response = query_engine.query(\"What did the author do growing up?\")\n",
|
||||
"print(response)\n"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "d0bZcv8fb9mL"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"### Langchain JS"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "xypvNdHnb-Yy"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"### Langchain JS"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "R55mK2vCcBN2"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import { ChatOpenAI } from \"@langchain/openai\";\n",
|
||||
"\n",
|
||||
|
|
@ -359,24 +350,24 @@
|
|||
"const message = await model.invoke(\"Hi there!\");\n",
|
||||
"\n",
|
||||
"console.log(message);\n"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "R55mK2vCcBN2"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"### OpenAI JS"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "nC4bLifCcCiW"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"### OpenAI JS"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "MICH8kIMcFpg"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"const { OpenAI } = require('openai');\n",
|
||||
"\n",
|
||||
|
|
@ -398,24 +389,24 @@
|
|||
"}\n",
|
||||
"\n",
|
||||
"main();\n"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "MICH8kIMcFpg"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"### Anthropic SDK"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "D1Q07pEAcGTb"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"### Anthropic SDK"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "qBjFcAvgcI3t"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import os\n",
|
||||
"\n",
|
||||
|
|
@ -423,7 +414,7 @@
|
|||
"\n",
|
||||
"client = Anthropic(\n",
|
||||
" base_url=\"http://localhost:4000\", # proxy endpoint\n",
|
||||
" api_key=\"sk-s4xN1IiLTCytwtZFJaYQrA\", # litellm proxy virtual key\n",
|
||||
" api_key=\"sk-test-proxy-key-123\", # litellm proxy virtual key (example)\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"message = client.messages.create(\n",
|
||||
|
|
@ -437,33 +428,33 @@
|
|||
" model=\"claude-3-opus-20240229\",\n",
|
||||
")\n",
|
||||
"print(message.content)"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "qBjFcAvgcI3t"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"## /embeddings"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "dFAR4AJGcONI"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"## /embeddings"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"### OpenAI Python SDK"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "lgNoM281cRzR"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"### OpenAI Python SDK"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "NY3DJhPfcQhA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import openai\n",
|
||||
"from openai import OpenAI\n",
|
||||
|
|
@ -478,24 +469,24 @@
|
|||
")\n",
|
||||
"\n",
|
||||
"print(response)\n"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "NY3DJhPfcQhA"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"### Langchain Embeddings"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "hmbg-DW6cUZs"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"### Langchain Embeddings"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "lX2S8Nl1cWVP"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from langchain.embeddings import OpenAIEmbeddings\n",
|
||||
"\n",
|
||||
|
|
@ -526,24 +517,22 @@
|
|||
"\n",
|
||||
"print(f\"TITAN EMBEDDINGS\")\n",
|
||||
"print(query_result[:5])"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "lX2S8Nl1cWVP"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"### Curl Request"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "oqGbWBCQcYfd"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"### Curl Request"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "7rkIMV9LcdwQ"
|
||||
},
|
||||
"source": [
|
||||
"\n",
|
||||
"\n",
|
||||
|
|
@ -556,10 +545,21 @@
|
|||
" }'\n",
|
||||
"```\n",
|
||||
"\n"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "7rkIMV9LcdwQ"
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"provenance": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"name": "python"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
|
|
|
|||
|
|
@ -34,8 +34,8 @@ RUN pip wheel --no-cache-dir --wheel-dir=/wheels/ -r requirements.txt
|
|||
# Runtime stage
|
||||
FROM $LITELLM_RUNTIME_IMAGE AS runtime
|
||||
|
||||
# Update dependencies and clean up
|
||||
RUN apk upgrade --no-cache
|
||||
# Update dependencies and clean up, install libsndfile for audio processing
|
||||
RUN apk upgrade --no-cache && apk add --no-cache libsndfile
|
||||
|
||||
WORKDIR /app
|
||||
|
||||
|
|
|
|||
|
|
@ -79,7 +79,7 @@ ENV PRISMA_BINARY_CACHE_DIR=/app/.cache/prisma-python/binaries \
|
|||
XDG_CACHE_HOME=/app/.cache \
|
||||
PATH="/usr/lib/python3.13/site-packages/nodejs/bin:${PATH}"
|
||||
|
||||
RUN pip install --no-cache-dir prisma==0.11.0 nodejs-bin==18.4.0a4 \
|
||||
RUN pip install --no-cache-dir prisma==0.11.0 nodejs-wheel-binaries==24.12.0 \
|
||||
&& mkdir -p /app/.cache/npm
|
||||
|
||||
RUN NPM_CONFIG_CACHE=/app/.cache/npm \
|
||||
|
|
|
|||
|
|
@ -6,7 +6,7 @@ authors:
|
|||
- name: Sameer Kankute
|
||||
title: SWE @ LiteLLM (LLM Translation)
|
||||
url: https://www.linkedin.com/in/sameer-kankute/
|
||||
image_url: https://media.licdn.com/dms/image/v2/D4D03AQHB_loQYd5gjg/profile-displayphoto-shrink_800_800/profile-displayphoto-shrink_800_800/0/1719137160975?e=1765411200&v=beta&t=c8396f--_lH6Fb_pVvx_jGholPfcl0bvwmNynbNdnII
|
||||
image_url: https://pbs.twimg.com/profile_images/2001352686994907136/ONgNuSk5_400x400.jpg
|
||||
- name: Krrish Dholakia
|
||||
title: "CEO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
|
|
|
|||
|
|
@ -6,7 +6,7 @@ authors:
|
|||
- name: Sameer Kankute
|
||||
title: SWE @ LiteLLM (LLM Translation)
|
||||
url: https://www.linkedin.com/in/sameer-kankute/
|
||||
image_url: https://media.licdn.com/dms/image/v2/D4D03AQHB_loQYd5gjg/profile-displayphoto-shrink_800_800/profile-displayphoto-shrink_800_800/0/1719137160975?e=1765411200&v=beta&t=c8396f--_lH6Fb_pVvx_jGholPfcl0bvwmNynbNdnII
|
||||
image_url: https://pbs.twimg.com/profile_images/2001352686994907136/ONgNuSk5_400x400.jpg
|
||||
- name: Krrish Dholakia
|
||||
title: "CEO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
|
|
|
|||
254
docs/my-website/blog/gemini_3_flash/index.md
Normal file
|
|
@ -0,0 +1,254 @@
|
|||
---
|
||||
slug: gemini_3_flash
|
||||
title: "DAY 0 Support: Gemini 3 Flash on LiteLLM"
|
||||
date: 2025-12-17T10:00:00
|
||||
authors:
|
||||
- name: Sameer Kankute
|
||||
title: SWE @ LiteLLM (LLM Translation)
|
||||
url: https://www.linkedin.com/in/sameer-kankute/
|
||||
image_url: https://pbs.twimg.com/profile_images/2001352686994907136/ONgNuSk5_400x400.jpg
|
||||
- name: Krrish Dholakia
|
||||
title: "CEO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: "CTO, LiteLLM"
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
tags: [gemini, day 0 support, llms]
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Gemini 3 Flash Day 0 Support
|
||||
|
||||
LiteLLM now supports `gemini-3-flash-preview` and all the new API changes along with it.
|
||||
|
||||
:::note
|
||||
If you only want cost tracking, you need no change in your current Litellm version. But if you want the support for new features introduced along with it like thinking levels, you will need to use v1.80.8-stable.1 or above.
|
||||
:::
|
||||
|
||||
## Deploy this version
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="docker" label="Docker">
|
||||
|
||||
``` showLineNumbers title="docker run litellm"
|
||||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
ghcr.io/berriai/litellm:main-v1.80.8-stable.1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="pip" label="Pip">
|
||||
|
||||
``` showLineNumbers title="pip install litellm"
|
||||
pip install litellm==1.80.8.post1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## What's New
|
||||
|
||||
### 1. New Thinking Levels: `thinkingLevel` with MINIMAL & MEDIUM
|
||||
|
||||
Gemini 3 Flash introduces granular thinking control with `thinkingLevel` instead of `thinkingBudget`.
|
||||
- **MINIMAL**: Ultra-lightweight thinking for fast responses
|
||||
- **MEDIUM**: Balanced thinking for complex reasoning
|
||||
- **HIGH**: Maximum reasoning depth
|
||||
|
||||
LiteLLM automatically maps the OpenAI `reasoning_effort` parameter to Gemini's `thinkingLevel`, so you can use familiar `reasoning_effort` values (`minimal`, `low`, `medium`, `high`) without changing your code!
|
||||
|
||||
### 2. Thought Signatures
|
||||
|
||||
Like `gemini-3-pro`, this model also includes thought signatures for tool calls. LiteLLM handles signature extraction and embedding internally. [Learn more about thought signatures](../gemini_3/index.md#thought-signatures).
|
||||
|
||||
**Edge Case Handling**: If thought signatures are missing in the request, LiteLLM adds a dummy signature ensuring the API call doesn't break
|
||||
|
||||
---
|
||||
## Supported Endpoints
|
||||
|
||||
LiteLLM provides **full end-to-end support** for Gemini 3 Flash on:
|
||||
|
||||
- ✅ `/v1/chat/completions` - OpenAI-compatible chat completions endpoint
|
||||
- ✅ `/v1/responses` - OpenAI Responses API endpoint (streaming and non-streaming)
|
||||
- ✅ [`/v1/messages`](../../docs/anthropic_unified) - Anthropic-compatible messages endpoint
|
||||
- ✅ `/v1/generateContent` – [Google Gemini API](../../docs/generateContent.md) compatible endpoint
|
||||
All endpoints support:
|
||||
- Streaming and non-streaming responses
|
||||
- Function calling with thought signatures
|
||||
- Multi-turn conversations
|
||||
- All Gemini 3-specific features
|
||||
- Converstion of provider specific thinking related param to thinkingLevel
|
||||
|
||||
## Quick Start
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
**Basic Usage with MEDIUM thinking (NEW)**
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
# No need to make any changes to your code as we map openai reasoning param to thinkingLevel
|
||||
response = completion(
|
||||
model="gemini/gemini-3-flash-preview",
|
||||
messages=[{"role": "user", "content": "Solve this complex math problem: 25 * 4 + 10"}],
|
||||
reasoning_effort="medium", # NEW: MEDIUM thinking level
|
||||
)
|
||||
|
||||
print(response.choices[0].message.content)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="proxy" label="PROXY">
|
||||
|
||||
**1. Setup config.yaml**
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: gemini-3-flash
|
||||
litellm_params:
|
||||
model: gemini/gemini-3-flash-preview
|
||||
api_key: os.environ/GEMINI_API_KEY
|
||||
```
|
||||
|
||||
**2. Start proxy**
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
**3. Call with MEDIUM thinking**
|
||||
|
||||
```bash
|
||||
curl -X POST http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer <YOUR-LITELLM-KEY>" \
|
||||
-d '{
|
||||
"model": "gemini-3-flash",
|
||||
"messages": [{"role": "user", "content": "Complex reasoning task"}],
|
||||
"reasoning_effort": "medium"
|
||||
}'
|
||||
``'
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
---
|
||||
|
||||
## All `reasoning_effort` Levels
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="minimal" label="MINIMAL">
|
||||
|
||||
**Ultra-fast, minimal reasoning**
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="gemini/gemini-3-flash-preview",
|
||||
messages=[{"role": "user", "content": "What's 2+2?"}],
|
||||
reasoning_effort="minimal",
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="low" label="LOW">
|
||||
|
||||
**Simple instruction following**
|
||||
|
||||
```python
|
||||
response = completion(
|
||||
model="gemini/gemini-3-flash-preview",
|
||||
messages=[{"role": "user", "content": "Write a haiku about coding"}],
|
||||
reasoning_effort="low",
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="medium" label="MEDIUM (NEW)">
|
||||
|
||||
**Balanced reasoning for complex tasks** ✨
|
||||
|
||||
```python
|
||||
response = completion(
|
||||
model="gemini/gemini-3-flash-preview",
|
||||
messages=[{"role": "user", "content": "Analyze this dataset and find patterns"}],
|
||||
reasoning_effort="medium", # NEW!
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="high" label="HIGH">
|
||||
|
||||
**Maximum reasoning depth**
|
||||
|
||||
```python
|
||||
response = completion(
|
||||
model="gemini/gemini-3-flash-preview",
|
||||
messages=[{"role": "user", "content": "Prove this mathematical theorem"}],
|
||||
reasoning_effort="high",
|
||||
)
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
---
|
||||
|
||||
## Key Features
|
||||
|
||||
✅ **Thinking Levels**: MINIMAL, LOW, MEDIUM, HIGH
|
||||
✅ **Thought Signatures**: Track reasoning with unique identifiers
|
||||
✅ **Seamless Integration**: Works with existing OpenAI-compatible client
|
||||
✅ **Backward Compatible**: Gemini 2.5 models continue using `thinkingBudget`
|
||||
|
||||
---
|
||||
|
||||
## Installation
|
||||
|
||||
```bash
|
||||
pip install litellm --upgrade
|
||||
```
|
||||
|
||||
```python
|
||||
import litellm
|
||||
from litellm import completion
|
||||
|
||||
response = completion(
|
||||
model="gemini/gemini-3-flash-preview",
|
||||
messages=[{"role": "user", "content": "Your question here"}],
|
||||
reasoning_effort="medium", # Use MEDIUM thinking
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
:::note
|
||||
If using this model via vertex_ai, keep the location as global as this is the only supported location as of now.
|
||||
:::
|
||||
|
||||
|
||||
## `reasoning_effort` Mapping for Gemini 3+
|
||||
|
||||
| reasoning_effort | thinking_level |
|
||||
|------------------|----------------|
|
||||
| `minimal` | `minimal` |
|
||||
| `low` | `low` |
|
||||
| `medium` | `medium` |
|
||||
| `high` | `high` |
|
||||
| `disable` | `minimal` |
|
||||
| `none` | `minimal` |
|
||||
|
||||
|
|
@ -60,6 +60,58 @@ Each machine deploying LiteLLM had the following specs:
|
|||
- Database: PostgreSQL
|
||||
- Redis: Not used
|
||||
|
||||
## Infrastructure Recommendations
|
||||
|
||||
Recommended specifications based on benchmark results and industry standards for API gateway deployments.
|
||||
|
||||
### PostgreSQL
|
||||
|
||||
Required for authentication, key management, and usage tracking.
|
||||
|
||||
| Workload | CPU | RAM | Storage | Connections |
|
||||
|----------|-----|-----|---------|-------------|
|
||||
| 1-2K RPS | 4-8 cores | 16GB | 200GB SSD (3000+ IOPS) | 100-200 |
|
||||
| 2-5K RPS | 8 cores | 16-32GB | 500GB SSD (5000+ IOPS) | 200-500 |
|
||||
| 5K+ RPS | 16+ cores | 32-64GB | 1TB+ SSD (10000+ IOPS) | 500+ |
|
||||
|
||||
**Configuration:** Set `proxy_batch_write_at: 60` to batch writes and reduce DB load. Total connections = pool limit × instances.
|
||||
|
||||
### Redis (Recommended)
|
||||
|
||||
Redis was not used in these benchmarks but provides significant production benefits: 60-80% reduced DB load.
|
||||
|
||||
| Workload | CPU | RAM |
|
||||
|----------|-----|-----|
|
||||
| 1-2K RPS | 2-4 cores | 8GB |
|
||||
| 2-5K RPS | 4 cores | 16GB |
|
||||
| 5K+ RPS | 8+ cores | 32GB+ |
|
||||
|
||||
**Requirements:** Redis 7.0+, AOF persistence enabled, `allkeys-lru` eviction policy.
|
||||
|
||||
**Configuration:**
|
||||
```yaml
|
||||
router_settings:
|
||||
redis_host: os.environ/REDIS_HOST
|
||||
redis_port: os.environ/REDIS_PORT
|
||||
redis_password: os.environ/REDIS_PASSWORD
|
||||
|
||||
litellm_settings:
|
||||
cache: True
|
||||
cache_params:
|
||||
type: redis
|
||||
host: os.environ/REDIS_HOST
|
||||
port: os.environ/REDIS_PORT
|
||||
password: os.environ/REDIS_PASSWORD
|
||||
```
|
||||
|
||||
:::tip
|
||||
Use `redis_host`, `redis_port`, and `redis_password` instead of `redis_url` for ~80 RPS better performance.
|
||||
:::
|
||||
|
||||
**Scaling:** DB connections scale linearly with instances. Consider PostgreSQL read replicas beyond 5K RPS.
|
||||
|
||||
See [Production Configuration](./proxy/prod) for detailed best practices.
|
||||
|
||||
## Locust Settings
|
||||
|
||||
- 1000 Users
|
||||
|
|
|
|||
|
|
@ -16,7 +16,7 @@ LiteLLM provides image editing functionality that maps to OpenAI's `/images/edit
|
|||
| Supported operations | Create image edits | Single and multiple images supported |
|
||||
| Supported LiteLLM SDK Versions | 1.63.8+ | Gemini support requires 1.79.3+ |
|
||||
| Supported LiteLLM Proxy Versions | 1.71.1+ | Gemini support requires 1.79.3+ |
|
||||
| Supported LLM providers | **OpenAI**, **Gemini (Google AI Studio)**, **Vertex AI** | Gemini supports the new `gemini-2.5-flash-image` family. Vertex AI supports both Gemini and Imagen models. |
|
||||
| Supported LLM providers | **OpenAI**, **Gemini (Google AI Studio)**, **Vertex AI**, **Stability AI**, **AWS Bedrock (Stability)** | Gemini supports the new `gemini-2.5-flash-image` family. Vertex AI supports both Gemini and Imagen models. Stability AI and Bedrock Stability support various image editing operations. |
|
||||
|
||||
#### ⚡️See all supported models and providers at [models.litellm.ai](https://models.litellm.ai/)
|
||||
|
||||
|
|
|
|||
238
docs/my-website/docs/observability/azure_sentinel.md
Normal file
|
|
@ -0,0 +1,238 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Azure Sentinel
|
||||
|
||||
<Image img={require('../../img/sentinel.png')} />
|
||||
|
||||
LiteLLM supports logging to Azure Sentinel via the Azure Monitor Logs Ingestion API. Azure Sentinel uses Log Analytics workspaces for data storage, so logs sent to the workspace will be available in Sentinel for security monitoring and analysis.
|
||||
|
||||
## Azure Sentinel Integration
|
||||
|
||||
| Feature | Details |
|
||||
|---------|---------|
|
||||
| **What is logged** | [StandardLoggingPayload](../proxy/logging_spec) |
|
||||
| **Events** | Success + Failure |
|
||||
| **Product Link** | [Azure Sentinel](https://learn.microsoft.com/en-us/azure/sentinel/overview) |
|
||||
| **API Reference** | [Logs Ingestion API](https://learn.microsoft.com/en-us/azure/azure-monitor/logs/logs-ingestion-api-overview) |
|
||||
|
||||
We will use the `--config` to set `litellm.callbacks = ["azure_sentinel"]` this will log all successful and failed LLM calls to Azure Sentinel.
|
||||
|
||||
**Step 1**: Create a `config.yaml` file and set `litellm_settings`: `callbacks`
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-3.5-turbo
|
||||
litellm_params:
|
||||
model: gpt-3.5-turbo
|
||||
litellm_settings:
|
||||
callbacks: ["azure_sentinel"] # logs llm success + failure logs to Azure Sentinel
|
||||
```
|
||||
|
||||
**Step 2**: Set Up Azure Resources
|
||||
|
||||
Before using the Logs Ingestion API, you need to set up the following in Azure:
|
||||
|
||||
1. **Create a Log Analytics Workspace** (if you don't have one)
|
||||
2. **Create a Custom Table** in your Log Analytics workspace (e.g., `LiteLLM_CL`)
|
||||
3. **Create a Data Collection Rule (DCR)** with:
|
||||
- Stream declaration matching your data structure
|
||||
- Transformation to map data to your custom table
|
||||
- Access granted to your app registration
|
||||
4. **Register an Application** in Microsoft Entra ID (Azure AD) with:
|
||||
- Client ID
|
||||
- Client Secret
|
||||
- Permissions to write to the DCR
|
||||
|
||||
For detailed setup instructions, see the [Microsoft documentation on Logs Ingestion API](https://learn.microsoft.com/en-us/azure/azure-monitor/logs/logs-ingestion-api-overview).
|
||||
|
||||
**Step 3**: Set Required Environment Variables
|
||||
|
||||
Set the following environment variables with your Azure credentials:
|
||||
|
||||
```shell showLineNumbers title="Environment Variables"
|
||||
# Required: Data Collection Rule (DCR) configuration
|
||||
AZURE_SENTINEL_DCR_IMMUTABLE_ID="dcr-xxxxxxxxxxxxxxxxxxxxxxxxxxxxx" # DCR Immutable ID from Azure portal
|
||||
AZURE_SENTINEL_STREAM_NAME="Custom-LiteLLM_CL_CL" # Stream name from your DCR
|
||||
AZURE_SENTINEL_ENDPOINT="https://your-dcr-endpoint.eastus-1.ingest.monitor.azure.com" # DCR logs ingestion endpoint (NOT the DCE endpoint)
|
||||
|
||||
# Required: OAuth2 Authentication (App Registration)
|
||||
AZURE_SENTINEL_TENANT_ID="your-tenant-id" # Azure Tenant ID
|
||||
AZURE_SENTINEL_CLIENT_ID="your-client-id" # Application (client) ID
|
||||
AZURE_SENTINEL_CLIENT_SECRET="your-client-secret" # Client secret value
|
||||
|
||||
```
|
||||
|
||||
**Note**: The `AZURE_SENTINEL_ENDPOINT` should be the DCR's logs ingestion endpoint (found in the DCR Overview page), NOT the Data Collection Endpoint (DCE). The DCR endpoint is associated with your specific DCR and looks like: `https://your-dcr-endpoint.{region}-1.ingest.monitor.azure.com`
|
||||
|
||||
**Step 4**: Start the proxy and make a test request
|
||||
|
||||
Start proxy
|
||||
|
||||
```shell showLineNumbers title="Start Proxy"
|
||||
litellm --config config.yaml --debug
|
||||
```
|
||||
|
||||
Test Request
|
||||
|
||||
```shell showLineNumbers title="Test Request"
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "gpt-3.5-turbo",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"your-custom-metadata": "custom-field",
|
||||
}
|
||||
}'
|
||||
```
|
||||
|
||||
**Step 5**: View logs in Azure Sentinel
|
||||
|
||||
1. Navigate to your Azure Sentinel workspace in the Azure portal
|
||||
2. Go to "Logs" and query your custom table (e.g., `LiteLLM_CL`)
|
||||
3. Run a query like:
|
||||
|
||||
```kusto showLineNumbers title="KQL Query"
|
||||
LiteLLM_CL
|
||||
| where TimeGenerated > ago(1h)
|
||||
| project TimeGenerated, model, status, total_tokens, response_cost
|
||||
| order by TimeGenerated desc
|
||||
```
|
||||
|
||||
You should see following logs in Azure Workspace.
|
||||
|
||||
<Image img={require('../../img/sentinel.png')} />
|
||||
|
||||
## Environment Variables
|
||||
|
||||
| Environment Variable | Description | Default Value | Required |
|
||||
|---------------------|-------------|---------------|----------|
|
||||
| `AZURE_SENTINEL_DCR_IMMUTABLE_ID` | Data Collection Rule (DCR) Immutable ID | None | ✅ Yes |
|
||||
| `AZURE_SENTINEL_ENDPOINT` | DCR logs ingestion endpoint URL (from DCR Overview page) | None | ✅ Yes |
|
||||
| `AZURE_SENTINEL_STREAM_NAME` | Stream name from DCR (e.g., "Custom-LiteLLM_CL_CL") | "Custom-LiteLLM" | ❌ No |
|
||||
| `AZURE_SENTINEL_TENANT_ID` | Azure Tenant ID for OAuth2 authentication | None (falls back to `AZURE_TENANT_ID`) | ✅ Yes |
|
||||
| `AZURE_SENTINEL_CLIENT_ID` | Application (client) ID for OAuth2 authentication | None (falls back to `AZURE_CLIENT_ID`) | ✅ Yes |
|
||||
| `AZURE_SENTINEL_CLIENT_SECRET` | Client secret for OAuth2 authentication | None (falls back to `AZURE_CLIENT_SECRET`) | ✅ Yes |
|
||||
|
||||
## How It Works
|
||||
|
||||
The Azure Sentinel integration uses the [Azure Monitor Logs Ingestion API](https://learn.microsoft.com/en-us/azure/azure-monitor/logs/logs-ingestion-api-overview) to send logs to your Log Analytics workspace. The integration:
|
||||
|
||||
- Authenticates using OAuth2 client credentials flow with your app registration
|
||||
- Sends logs to the Data Collection Rule (DCR) endpoint
|
||||
- Batches logs for efficient transmission
|
||||
- Sends logs in the [StandardLoggingPayload](../proxy/logging_spec) format
|
||||
- Automatically handles both success and failure events
|
||||
- Caches OAuth2 tokens and refreshes them automatically
|
||||
|
||||
Logs sent to the Log Analytics workspace are automatically available in Azure Sentinel for security monitoring, threat detection, and analysis.
|
||||
|
||||
## Azure Sentinel Setup Guide
|
||||
|
||||
Follow this step-by-step guide to set up Azure Sentinel with LiteLLM.
|
||||
|
||||
### Step 1: Create a Log Analytics Workspace
|
||||
|
||||
1. Navigate to [https://portal.azure.com/#home](https://portal.azure.com/#home)
|
||||
|
||||

|
||||
|
||||
2. Search for "Log Analytics workspaces" and click "Create"
|
||||
|
||||

|
||||
|
||||
3. Enter a name for your workspace (e.g., "litellm-sentinel-prod")
|
||||
|
||||

|
||||
|
||||
4. Click "Review + Create"
|
||||
|
||||

|
||||
|
||||
### Step 2: Create a Custom Table
|
||||
|
||||
1. Go to your Log Analytics workspace and click "Tables"
|
||||
|
||||

|
||||
|
||||
2. Click "Create" → "New custom log (Direct Ingest)"
|
||||
|
||||

|
||||
|
||||
3. Enter a table name (e.g., "LITELLM_PROD_CL")
|
||||
|
||||

|
||||
|
||||
### Step 3: Create a Data Collection Rule (DCR)
|
||||
|
||||
1. Click "Create a new data collection rule"
|
||||
|
||||

|
||||
|
||||
2. Enter a name for the DCR (e.g., "litellm-prod")
|
||||
|
||||

|
||||
|
||||
3. Select a Data Collection Endpoint
|
||||
|
||||

|
||||
|
||||
4. Upload the sample JSON file for schema (use the [example_standard_logging_payload.json](https://github.com/BerriAI/litellm/blob/main/litellm/integrations/azure_sentinel/example_standard_logging_payload.json) file)
|
||||
|
||||

|
||||
|
||||
5. Click "Next" and then "Create"
|
||||
|
||||

|
||||
|
||||
### Step 4: Get the DCR Immutable ID and Logs Ingestion Endpoint
|
||||
|
||||
1. Go to "Data Collection Rules" and select your DCR
|
||||
|
||||

|
||||
|
||||
2. Copy the **DCR Immutable ID** (starts with `dcr-`)
|
||||
|
||||

|
||||
|
||||
3. Copy the **Logs Ingestion Endpoint** URL
|
||||
|
||||

|
||||
|
||||
### Step 5: Get the Stream Name
|
||||
|
||||
1. Click "JSON View" in the DCR
|
||||
|
||||

|
||||
|
||||
2. Find the **Stream Name** in the `streamDeclarations` section (e.g., "Custom-LITELLM_PROD_CL_CL")
|
||||
|
||||

|
||||
|
||||
### Step 6: Register an App and Grant Permissions
|
||||
|
||||
1. Go to **Microsoft Entra ID** → **App registrations** → **New registration**
|
||||
2. Create a new app and note the **Client ID** and **Tenant ID**
|
||||
3. Go to **Certificates & secrets** → Create a new client secret and copy the **Secret Value**
|
||||
4. Go back to your DCR → **Access Control (IAM)** → **Add role assignment**
|
||||
5. Assign the **"Monitoring Metrics Publisher"** role to your app registration
|
||||
|
||||
### Summary: Where to Find Each Value
|
||||
|
||||
| Environment Variable | Where to Find It |
|
||||
|---------------------|------------------|
|
||||
| `AZURE_SENTINEL_DCR_IMMUTABLE_ID` | DCR Overview page → Immutable ID (starts with `dcr-`) |
|
||||
| `AZURE_SENTINEL_ENDPOINT` | DCR Overview page → Logs Ingestion Endpoint |
|
||||
| `AZURE_SENTINEL_STREAM_NAME` | DCR JSON View → `streamDeclarations` section |
|
||||
| `AZURE_SENTINEL_TENANT_ID` | App Registration → Overview → Directory (tenant) ID |
|
||||
| `AZURE_SENTINEL_CLIENT_ID` | App Registration → Overview → Application (client) ID |
|
||||
| `AZURE_SENTINEL_CLIENT_SECRET` | App Registration → Certificates & secrets → Secret Value |
|
||||
|
||||
For more details, refer to the [Microsoft Logs Ingestion API documentation](https://learn.microsoft.com/en-us/azure/azure-monitor/logs/logs-ingestion-api-overview).
|
||||
|
|
@ -65,6 +65,52 @@ Start your LiteLLM proxy with the configuration:
|
|||
litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
## Setup on UI
|
||||
|
||||
1\. Click "Settings"
|
||||
|
||||

|
||||
|
||||
|
||||
2\. Click "Logging & Alerts"
|
||||
|
||||

|
||||
|
||||
|
||||
3\. Click "CloudZero Cost Tracking"
|
||||
|
||||

|
||||
|
||||
|
||||
4\. Click "Add CloudZero Integration"
|
||||
|
||||

|
||||
|
||||
|
||||
5\. Enter your CloudZero API Key.
|
||||
|
||||

|
||||
|
||||
|
||||
6\. Enter your CloudZero Connection ID.
|
||||
|
||||

|
||||
|
||||
|
||||
7\. Click "Create"
|
||||
|
||||

|
||||
|
||||
|
||||
8\. Test your payload with "Run Dry Run Simulation"
|
||||
|
||||

|
||||
|
||||
|
||||
10\. Click "Export Data Now" to export to CLoudZero
|
||||
|
||||

|
||||
|
||||
## Testing Your Setup
|
||||
|
||||
### Dry Run Export
|
||||
|
|
|
|||
|
|
@ -106,7 +106,7 @@ model_list:
|
|||
aws_region_name: us-west-2
|
||||
aws_session_name: "my-test-session"
|
||||
aws_role_name: "arn:aws:iam::335785316107:role/litellm-github-unit-tests-circleci"
|
||||
aws_web_identity_token: "oidc/circleci_v2/"
|
||||
aws_web_identity_token: "oidc/example-provider/"
|
||||
```
|
||||
|
||||
#### Amazon IAM Role Configuration for CircleCI v2 -> Bedrock
|
||||
|
|
|
|||
364
docs/my-website/docs/providers/aws_polly.md
Normal file
|
|
@ -0,0 +1,364 @@
|
|||
# AWS Polly Text to Speech (tts)
|
||||
|
||||
## Overview
|
||||
|
||||
| Property | Details |
|
||||
|-------|-------|
|
||||
| Description | Convert text to natural-sounding speech using AWS Polly's neural and standard TTS engines |
|
||||
| Provider Route on LiteLLM | `aws_polly/` |
|
||||
| Supported Operations | `/audio/speech` |
|
||||
| Link to Provider Doc | [AWS Polly SynthesizeSpeech ↗](https://docs.aws.amazon.com/polly/latest/dg/API_SynthesizeSpeech.html) |
|
||||
|
||||
## Quick Start
|
||||
|
||||
### **LiteLLM SDK**
|
||||
|
||||
```python showLineNumbers title="SDK Usage"
|
||||
import litellm
|
||||
from pathlib import Path
|
||||
import os
|
||||
|
||||
# Set environment variables
|
||||
os.environ["AWS_ACCESS_KEY_ID"] = ""
|
||||
os.environ["AWS_SECRET_ACCESS_KEY"] = ""
|
||||
os.environ["AWS_REGION_NAME"] = "us-east-1"
|
||||
|
||||
# AWS Polly call
|
||||
speech_file_path = Path(__file__).parent / "speech.mp3"
|
||||
response = litellm.speech(
|
||||
model="aws_polly/neural",
|
||||
voice="Joanna",
|
||||
input="the quick brown fox jumped over the lazy dogs",
|
||||
)
|
||||
response.stream_to_file(speech_file_path)
|
||||
```
|
||||
|
||||
### **LiteLLM PROXY**
|
||||
|
||||
```yaml showLineNumbers title="proxy_config.yaml"
|
||||
model_list:
|
||||
- model_name: polly-neural
|
||||
litellm_params:
|
||||
model: aws_polly/neural
|
||||
aws_access_key_id: "os.environ/AWS_ACCESS_KEY_ID"
|
||||
aws_secret_access_key: "os.environ/AWS_SECRET_ACCESS_KEY"
|
||||
aws_region_name: "us-east-1"
|
||||
```
|
||||
|
||||
## Polly Engines
|
||||
|
||||
AWS Polly supports different speech synthesis engines. Specify the engine in the model name:
|
||||
|
||||
| Model | Engine | Cost (per 1M chars) | Description |
|
||||
|-------|--------|---------------------|-------------|
|
||||
| `aws_polly/standard` | Standard | $4.00 | Original Polly voices, faster and lowest cost |
|
||||
| `aws_polly/neural` | Neural | $16.00 | More natural, human-like speech (recommended) |
|
||||
| `aws_polly/generative` | Generative | $30.00 | Most expressive, highest quality (limited voices) |
|
||||
| `aws_polly/long-form` | Long-form | $100.00 | Optimized for long content like articles |
|
||||
|
||||
### **LiteLLM SDK**
|
||||
|
||||
```python showLineNumbers title="Using Different Engines"
|
||||
import litellm
|
||||
|
||||
# Neural engine (recommended)
|
||||
response = litellm.speech(
|
||||
model="aws_polly/neural",
|
||||
voice="Joanna",
|
||||
input="Hello world",
|
||||
)
|
||||
|
||||
# Standard engine (lower cost)
|
||||
response = litellm.speech(
|
||||
model="aws_polly/standard",
|
||||
voice="Joanna",
|
||||
input="Hello world",
|
||||
)
|
||||
|
||||
# Generative engine (highest quality)
|
||||
response = litellm.speech(
|
||||
model="aws_polly/generative",
|
||||
voice="Matthew",
|
||||
input="Hello world",
|
||||
)
|
||||
```
|
||||
|
||||
### **LiteLLM PROXY**
|
||||
|
||||
```yaml showLineNumbers title="proxy_config.yaml"
|
||||
model_list:
|
||||
- model_name: polly-neural
|
||||
litellm_params:
|
||||
model: aws_polly/neural
|
||||
aws_region_name: "us-east-1"
|
||||
- model_name: polly-standard
|
||||
litellm_params:
|
||||
model: aws_polly/standard
|
||||
aws_region_name: "us-east-1"
|
||||
- model_name: polly-generative
|
||||
litellm_params:
|
||||
model: aws_polly/generative
|
||||
aws_region_name: "us-east-1"
|
||||
```
|
||||
|
||||
## Available Voices
|
||||
|
||||
### Native Polly Voices
|
||||
|
||||
AWS Polly has many voices across different languages. Here are popular US English voices:
|
||||
|
||||
| Voice | Gender | Engine Support |
|
||||
|-------|--------|----------------|
|
||||
| `Joanna` | Female | Neural, Standard |
|
||||
| `Matthew` | Male | Neural, Standard, Generative |
|
||||
| `Ivy` | Female (child) | Neural, Standard |
|
||||
| `Kendra` | Female | Neural, Standard |
|
||||
| `Amy` | Female (British) | Neural, Standard |
|
||||
| `Brian` | Male (British) | Neural, Standard |
|
||||
|
||||
### **LiteLLM SDK**
|
||||
|
||||
```python showLineNumbers title="Using Native Polly Voices"
|
||||
import litellm
|
||||
|
||||
# US English female
|
||||
response = litellm.speech(
|
||||
model="aws_polly/neural",
|
||||
voice="Joanna",
|
||||
input="Hello from Joanna",
|
||||
)
|
||||
|
||||
# US English male
|
||||
response = litellm.speech(
|
||||
model="aws_polly/neural",
|
||||
voice="Matthew",
|
||||
input="Hello from Matthew",
|
||||
)
|
||||
|
||||
# British English female
|
||||
response = litellm.speech(
|
||||
model="aws_polly/neural",
|
||||
voice="Amy",
|
||||
input="Hello from Amy",
|
||||
)
|
||||
```
|
||||
|
||||
### **LiteLLM PROXY**
|
||||
|
||||
```yaml showLineNumbers title="proxy_config.yaml"
|
||||
model_list:
|
||||
- model_name: polly-joanna
|
||||
litellm_params:
|
||||
model: aws_polly/neural
|
||||
voice: "Joanna"
|
||||
aws_region_name: "us-east-1"
|
||||
- model_name: polly-matthew
|
||||
litellm_params:
|
||||
model: aws_polly/neural
|
||||
voice: "Matthew"
|
||||
aws_region_name: "us-east-1"
|
||||
```
|
||||
|
||||
### OpenAI Voice Mappings
|
||||
|
||||
LiteLLM also supports OpenAI voice names, which are automatically mapped to Polly voices:
|
||||
|
||||
| OpenAI Voice | Maps to Polly Voice |
|
||||
|--------------|---------------------|
|
||||
| `alloy` | Joanna |
|
||||
| `echo` | Matthew |
|
||||
| `fable` | Amy |
|
||||
| `onyx` | Brian |
|
||||
| `nova` | Ivy |
|
||||
| `shimmer` | Kendra |
|
||||
|
||||
### **LiteLLM SDK**
|
||||
|
||||
```python showLineNumbers title="Using OpenAI Voice Names"
|
||||
import litellm
|
||||
|
||||
# These are equivalent
|
||||
response = litellm.speech(
|
||||
model="aws_polly/neural",
|
||||
voice="alloy", # Maps to Joanna
|
||||
input="Hello world",
|
||||
)
|
||||
|
||||
response = litellm.speech(
|
||||
model="aws_polly/neural",
|
||||
voice="Joanna", # Native Polly voice
|
||||
input="Hello world",
|
||||
)
|
||||
```
|
||||
|
||||
## SSML Support
|
||||
|
||||
AWS Polly supports SSML (Speech Synthesis Markup Language) for advanced control over speech output. LiteLLM automatically detects SSML input.
|
||||
|
||||
### **LiteLLM SDK**
|
||||
|
||||
```python showLineNumbers title="SSML Example"
|
||||
import litellm
|
||||
|
||||
ssml_input = """
|
||||
<speak>
|
||||
Hello, <break time="500ms"/>
|
||||
this is a test with <emphasis level="strong">emphasis</emphasis>
|
||||
and <prosody rate="slow">slower speech</prosody>.
|
||||
</speak>
|
||||
"""
|
||||
|
||||
response = litellm.speech(
|
||||
model="aws_polly/neural",
|
||||
voice="Joanna",
|
||||
input=ssml_input,
|
||||
)
|
||||
```
|
||||
|
||||
### **LiteLLM PROXY**
|
||||
|
||||
```bash showLineNumbers title="cURL Request with SSML"
|
||||
curl -X POST http://localhost:4000/v1/audio/speech \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "polly-neural",
|
||||
"voice": "Joanna",
|
||||
"input": "<speak>Hello <break time=\"500ms\"/> world</speak>"
|
||||
}' \
|
||||
--output speech.mp3
|
||||
```
|
||||
|
||||
## Supported Parameters
|
||||
|
||||
```python showLineNumbers title="All Parameters"
|
||||
response = litellm.speech(
|
||||
model="aws_polly/neural",
|
||||
voice="Joanna", # Required: Voice selection
|
||||
input="text to convert", # Required: Input text (or SSML)
|
||||
response_format="mp3", # Optional: mp3, ogg_vorbis, pcm
|
||||
|
||||
# AWS-specific parameters
|
||||
language_code="en-US", # Optional: Language code
|
||||
sample_rate="22050", # Optional: Sample rate in Hz
|
||||
)
|
||||
```
|
||||
|
||||
## Response Formats
|
||||
|
||||
| Format | Description |
|
||||
|--------|-------------|
|
||||
| `mp3` | MP3 audio (default) |
|
||||
| `ogg_vorbis` | Ogg Vorbis audio |
|
||||
| `pcm` | Raw PCM audio |
|
||||
|
||||
### **LiteLLM SDK**
|
||||
|
||||
```python showLineNumbers title="Different Response Formats"
|
||||
import litellm
|
||||
|
||||
# MP3 (default)
|
||||
response = litellm.speech(
|
||||
model="aws_polly/neural",
|
||||
voice="Joanna",
|
||||
input="Hello",
|
||||
response_format="mp3",
|
||||
)
|
||||
|
||||
# Ogg Vorbis
|
||||
response = litellm.speech(
|
||||
model="aws_polly/neural",
|
||||
voice="Joanna",
|
||||
input="Hello",
|
||||
response_format="ogg_vorbis",
|
||||
)
|
||||
```
|
||||
|
||||
## AWS Authentication
|
||||
|
||||
LiteLLM supports multiple AWS authentication methods.
|
||||
|
||||
### **LiteLLM SDK**
|
||||
|
||||
```python showLineNumbers title="Authentication Options"
|
||||
import litellm
|
||||
import os
|
||||
|
||||
# Option 1: Environment variables (recommended)
|
||||
os.environ["AWS_ACCESS_KEY_ID"] = "your-access-key"
|
||||
os.environ["AWS_SECRET_ACCESS_KEY"] = "your-secret-key"
|
||||
os.environ["AWS_REGION_NAME"] = "us-east-1"
|
||||
|
||||
response = litellm.speech(model="aws_polly/neural", voice="Joanna", input="Hello")
|
||||
|
||||
# Option 2: Pass credentials directly
|
||||
response = litellm.speech(
|
||||
model="aws_polly/neural",
|
||||
voice="Joanna",
|
||||
input="Hello",
|
||||
aws_access_key_id="your-access-key",
|
||||
aws_secret_access_key="your-secret-key",
|
||||
aws_region_name="us-east-1",
|
||||
)
|
||||
|
||||
# Option 3: IAM Role (when running on AWS)
|
||||
response = litellm.speech(
|
||||
model="aws_polly/neural",
|
||||
voice="Joanna",
|
||||
input="Hello",
|
||||
aws_region_name="us-east-1",
|
||||
)
|
||||
|
||||
# Option 4: AWS Profile
|
||||
response = litellm.speech(
|
||||
model="aws_polly/neural",
|
||||
voice="Joanna",
|
||||
input="Hello",
|
||||
aws_profile_name="my-profile",
|
||||
)
|
||||
```
|
||||
|
||||
### **LiteLLM PROXY**
|
||||
|
||||
```yaml showLineNumbers title="proxy_config.yaml"
|
||||
model_list:
|
||||
# Using environment variables
|
||||
- model_name: polly-neural
|
||||
litellm_params:
|
||||
model: aws_polly/neural
|
||||
aws_access_key_id: "os.environ/AWS_ACCESS_KEY_ID"
|
||||
aws_secret_access_key: "os.environ/AWS_SECRET_ACCESS_KEY"
|
||||
aws_region_name: "us-east-1"
|
||||
|
||||
# Using IAM Role (when proxy runs on AWS)
|
||||
- model_name: polly-neural-iam
|
||||
litellm_params:
|
||||
model: aws_polly/neural
|
||||
aws_region_name: "us-east-1"
|
||||
|
||||
# Using AWS Profile
|
||||
- model_name: polly-neural-profile
|
||||
litellm_params:
|
||||
model: aws_polly/neural
|
||||
aws_profile_name: "my-profile"
|
||||
```
|
||||
|
||||
## Async Support
|
||||
|
||||
```python showLineNumbers title="Async Usage"
|
||||
import litellm
|
||||
import asyncio
|
||||
|
||||
async def main():
|
||||
response = await litellm.aspeech(
|
||||
model="aws_polly/neural",
|
||||
voice="Joanna",
|
||||
input="Hello from async AWS Polly",
|
||||
aws_region_name="us-east-1",
|
||||
)
|
||||
|
||||
with open("output.mp3", "wb") as f:
|
||||
f.write(response.content)
|
||||
|
||||
asyncio.run(main())
|
||||
```
|
||||
|
|
@ -172,6 +172,125 @@ print(f"Results available at: {output_s3_uri}")
|
|||
|
||||
**Note:** The actual embedding results are stored in S3. When the job is completed, download the results from the S3 location specified in `status.metadata['output_file_id']`. The results will be in JSON/JSONL format containing the embedding vectors.
|
||||
|
||||
## Amazon Nova Multimodal Embeddings
|
||||
|
||||
Amazon Nova supports multimodal embeddings for text, images, video, and audio. It offers flexible embedding dimensions and purposes optimized for different use cases.
|
||||
|
||||
### Supported Features
|
||||
|
||||
- **Modalities**: Text, Image, Video, Audio
|
||||
- **Dimensions**: 256, 384, 1024, 3072 (default: 3072)
|
||||
- **Embedding Purposes**:
|
||||
- `GENERIC_INDEX` (default)
|
||||
- `GENERIC_RETRIEVAL`
|
||||
- `TEXT_RETRIEVAL`
|
||||
- `IMAGE_RETRIEVAL`
|
||||
- `VIDEO_RETRIEVAL`
|
||||
- `AUDIO_RETRIEVAL`
|
||||
- `CLASSIFICATION`
|
||||
- `CLUSTERING`
|
||||
|
||||
### Text Embedding
|
||||
|
||||
```python
|
||||
from litellm import embedding
|
||||
|
||||
response = embedding(
|
||||
model="bedrock/amazon.nova-2-multimodal-embeddings-v1:0",
|
||||
input=["Hello, world!"],
|
||||
aws_region_name="us-east-1",
|
||||
dimensions=1024, # Optional: 256, 384, 1024, or 3072
|
||||
)
|
||||
|
||||
print(response.data[0].embedding)
|
||||
```
|
||||
|
||||
### Image Embedding with Base64
|
||||
|
||||
Amazon Nova accepts images in base64 format using the standard data URL format:
|
||||
|
||||
```python
|
||||
import base64
|
||||
from litellm import embedding
|
||||
|
||||
# Method 1: Load image from file
|
||||
with open("image.jpg", "rb") as image_file:
|
||||
image_data = base64.b64encode(image_file.read()).decode('utf-8')
|
||||
# Create data URL with proper format
|
||||
image_base64 = f"data:image/jpeg;base64,{image_data}"
|
||||
|
||||
response = embedding(
|
||||
model="bedrock/amazon.nova-2-multimodal-embeddings-v1:0",
|
||||
input=[image_base64],
|
||||
aws_region_name="us-east-1",
|
||||
dimensions=1024,
|
||||
)
|
||||
|
||||
print(f"Image embedding: {response.data[0].embedding[:10]}...") # First 10 dimensions
|
||||
```
|
||||
|
||||
#### Supported Image Formats
|
||||
|
||||
Nova supports the following image formats:
|
||||
- JPEG: `data:image/jpeg;base64,...`
|
||||
- PNG: `data:image/png;base64,...`
|
||||
- GIF: `data:image/gif;base64,...`
|
||||
- WebP: `data:image/webp;base64,...`
|
||||
|
||||
#### Complete Example with Error Handling
|
||||
|
||||
```python
|
||||
import base64
|
||||
from litellm import embedding
|
||||
|
||||
def get_image_embedding(image_path, dimensions=1024):
|
||||
"""
|
||||
Get embedding for an image file.
|
||||
|
||||
Args:
|
||||
image_path: Path to the image file
|
||||
dimensions: Embedding dimension (256, 384, 1024, or 3072)
|
||||
|
||||
Returns:
|
||||
List of embedding values
|
||||
"""
|
||||
try:
|
||||
# Determine image format from file extension
|
||||
if image_path.lower().endswith('.png'):
|
||||
mime_type = "image/png"
|
||||
elif image_path.lower().endswith(('.jpg', '.jpeg')):
|
||||
mime_type = "image/jpeg"
|
||||
elif image_path.lower().endswith('.gif'):
|
||||
mime_type = "image/gif"
|
||||
elif image_path.lower().endswith('.webp'):
|
||||
mime_type = "image/webp"
|
||||
else:
|
||||
raise ValueError(f"Unsupported image format: {image_path}")
|
||||
|
||||
# Read and encode image
|
||||
with open(image_path, "rb") as image_file:
|
||||
image_data = base64.b64encode(image_file.read()).decode('utf-8')
|
||||
image_base64 = f"data:{mime_type};base64,{image_data}"
|
||||
|
||||
# Get embedding
|
||||
response = embedding(
|
||||
model="bedrock/amazon.nova-2-multimodal-embeddings-v1:0",
|
||||
input=[image_base64],
|
||||
aws_region_name="us-east-1",
|
||||
dimensions=dimensions,
|
||||
)
|
||||
|
||||
return response.data[0].embedding
|
||||
|
||||
except Exception as e:
|
||||
print(f"Error getting image embedding: {e}")
|
||||
raise
|
||||
|
||||
# Example usage
|
||||
image_embedding = get_image_embedding("photo.jpg", dimensions=1024)
|
||||
print(f"Got embedding with {len(image_embedding)} dimensions")
|
||||
```
|
||||
|
||||
### Error Handling
|
||||
|
||||
#### Common Errors
|
||||
|
|
|
|||
|
|
@ -11,6 +11,99 @@ LiteLLM supports all models on Databricks
|
|||
|
||||
:::
|
||||
|
||||
## Authentication
|
||||
|
||||
LiteLLM supports multiple authentication methods for Databricks, listed in order of preference:
|
||||
|
||||
### OAuth M2M (Recommended for Production)
|
||||
|
||||
OAuth Machine-to-Machine authentication using Service Principal credentials is the **recommended method for production** deployments per Databricks Partner requirements.
|
||||
|
||||
```python
|
||||
import os
|
||||
from litellm import completion
|
||||
|
||||
# Set OAuth credentials (Service Principal)
|
||||
os.environ["DATABRICKS_CLIENT_ID"] = "your-service-principal-application-id"
|
||||
os.environ["DATABRICKS_CLIENT_SECRET"] = "your-service-principal-secret"
|
||||
os.environ["DATABRICKS_API_BASE"] = "https://adb-xxx.azuredatabricks.net/serving-endpoints"
|
||||
|
||||
response = completion(
|
||||
model="databricks/databricks-dbrx-instruct",
|
||||
messages=[{"role": "user", "content": "Hello!"}],
|
||||
)
|
||||
```
|
||||
|
||||
### Personal Access Token (PAT)
|
||||
|
||||
PAT authentication is supported for development and testing scenarios.
|
||||
|
||||
```python
|
||||
import os
|
||||
from litellm import completion
|
||||
|
||||
os.environ["DATABRICKS_API_KEY"] = "dapi..." # Your Personal Access Token
|
||||
os.environ["DATABRICKS_API_BASE"] = "https://adb-xxx.azuredatabricks.net/serving-endpoints"
|
||||
|
||||
response = completion(
|
||||
model="databricks/databricks-dbrx-instruct",
|
||||
messages=[{"role": "user", "content": "Hello!"}],
|
||||
)
|
||||
```
|
||||
|
||||
### Databricks SDK Authentication (Automatic)
|
||||
|
||||
If no credentials are provided, LiteLLM will use the Databricks SDK for automatic authentication. This supports OAuth, Azure AD, and other unified auth methods configured in your environment.
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
# No environment variables needed - uses Databricks SDK unified auth
|
||||
# Requires: pip install databricks-sdk
|
||||
response = completion(
|
||||
model="databricks/databricks-dbrx-instruct",
|
||||
messages=[{"role": "user", "content": "Hello!"}],
|
||||
)
|
||||
```
|
||||
|
||||
## Custom User-Agent for Partner Attribution
|
||||
|
||||
If you're building a product on top of LiteLLM that integrates with Databricks, you can pass your own partner identifier for proper attribution in Databricks telemetry.
|
||||
|
||||
The partner name will be prefixed to the LiteLLM user agent:
|
||||
|
||||
```python
|
||||
# Via parameter
|
||||
response = completion(
|
||||
model="databricks/databricks-dbrx-instruct",
|
||||
messages=[{"role": "user", "content": "Hello!"}],
|
||||
user_agent="mycompany/1.0.0",
|
||||
)
|
||||
# Resulting User-Agent: mycompany_litellm/1.79.1
|
||||
|
||||
# Via environment variable
|
||||
os.environ["DATABRICKS_USER_AGENT"] = "mycompany/1.0.0"
|
||||
# Resulting User-Agent: mycompany_litellm/1.79.1
|
||||
```
|
||||
|
||||
| Input | Resulting User-Agent |
|
||||
|-------|---------------------|
|
||||
| (none) | `litellm/1.79.1` |
|
||||
| `mycompany/1.0.0` | `mycompany_litellm/1.79.1` |
|
||||
| `partner_product/2.5.0` | `partner_product_litellm/1.79.1` |
|
||||
| `acme` | `acme_litellm/1.79.1` |
|
||||
|
||||
**Note:** The version from your custom user agent is ignored; LiteLLM's version is always used.
|
||||
|
||||
## Security
|
||||
|
||||
LiteLLM automatically redacts sensitive information (tokens, secrets, API keys) from all debug logs to prevent credential leakage. This includes:
|
||||
|
||||
- Authorization headers
|
||||
- API keys and tokens
|
||||
- Client secrets
|
||||
- Personal access tokens (PATs)
|
||||
|
||||
## Usage
|
||||
|
||||
<Tabs>
|
||||
|
|
@ -51,6 +144,7 @@ response = completion(
|
|||
model: databricks/databricks-dbrx-instruct
|
||||
api_key: os.environ/DATABRICKS_API_KEY
|
||||
api_base: os.environ/DATABRICKS_API_BASE
|
||||
user_agent: "mycompany/1.0.0" # Optional: for partner attribution
|
||||
```
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -150,15 +150,15 @@ We support ALL Groq models, just set `groq/` as a prefix when sending completion
|
|||
|
||||
| Model Name | Usage |
|
||||
|--------------------|---------------------------------------------------------|
|
||||
| llama-3.1-8b-instant | `completion(model="groq/llama-3.1-8b-instant", messages)` |
|
||||
| llama-3.1-70b-versatile | `completion(model="groq/llama-3.1-70b-versatile", messages)` |
|
||||
| llama3-8b-8192 | `completion(model="groq/llama3-8b-8192", messages)` |
|
||||
| llama3-70b-8192 | `completion(model="groq/llama3-70b-8192", messages)` |
|
||||
| llama2-70b-4096 | `completion(model="groq/llama2-70b-4096", messages)` |
|
||||
| mixtral-8x7b-32768 | `completion(model="groq/mixtral-8x7b-32768", messages)` |
|
||||
| gemma-7b-it | `completion(model="groq/gemma-7b-it", messages)` |
|
||||
| moonshotai/kimi-k2-instruct | `completion(model="groq/moonshotai/kimi-k2-instruct", messages)` |
|
||||
| qwen3-32b | `completion(model="groq/qwen/qwen3-32b", messages)` |
|
||||
| llama-3.3-70b-versatile | `completion(model="groq/llama-3.3-70b-versatile", messages)` |
|
||||
| llama-3.1-8b-instant | `completion(model="groq/llama-3.1-8b-instant", messages)` |
|
||||
| meta-llama/llama-4-scout-17b-16e-instruct | `completion(model="groq/meta-llama/llama-4-scout-17b-16e-instruct", messages)` |
|
||||
| meta-llama/llama-4-maverick-17b-128e-instruct | `completion(model="groq/meta-llama/llama-4-maverick-17b-128e-instruct", messages)` |
|
||||
| meta-llama/llama-guard-4-12b | `completion(model="groq/meta-llama/llama-guard-4-12b", messages)` |
|
||||
| qwen/qwen3-32b | `completion(model="groq/qwen/qwen3-32b", messages)` |
|
||||
| moonshotai/kimi-k2-instruct-0905 | `completion(model="groq/moonshotai/kimi-k2-instruct-0905", messages)` |
|
||||
| openai/gpt-oss-120b | `completion(model="groq/openai/gpt-oss-120b", messages)` |
|
||||
| openai/gpt-oss-20b | `completion(model="groq/openai/gpt-oss-20b", messages)` |
|
||||
|
||||
## Groq - Tool / Function Calling Example
|
||||
|
||||
|
|
@ -261,31 +261,28 @@ if tool_calls:
|
|||
print("second response\n", second_response)
|
||||
```
|
||||
|
||||
## Groq - Vision Example
|
||||
## Groq - Vision Example
|
||||
|
||||
Select Groq models support vision. Check out their [model list](https://console.groq.com/docs/vision) for more details.
|
||||
Groq's Llama 4 models support vision. Check out their [model list](https://console.groq.com/docs/vision) for more details.
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="sdk" label="SDK">
|
||||
|
||||
```python
|
||||
from litellm import completion
|
||||
|
||||
import os
|
||||
import os
|
||||
from litellm import completion
|
||||
|
||||
os.environ["GROQ_API_KEY"] = "your-api-key"
|
||||
|
||||
# openai call
|
||||
response = completion(
|
||||
model = "groq/llama-3.2-11b-vision-preview",
|
||||
model = "groq/meta-llama/llama-4-scout-17b-16e-instruct",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "text",
|
||||
"text": "What’s in this image?"
|
||||
"text": "What's in this image?"
|
||||
},
|
||||
{
|
||||
"type": "image_url",
|
||||
|
|
|
|||
|
|
@ -623,6 +623,58 @@ display(styled_df)
|
|||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
## Function Calling
|
||||
|
||||
```python showLineNumbers title="Function Calling with Parallel Tool Calls"
|
||||
import litellm
|
||||
import json
|
||||
|
||||
tools = [
|
||||
{
|
||||
"type": "function",
|
||||
"name": "get_weather",
|
||||
"description": "Get current weather for a location",
|
||||
"parameters": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"location": {"type": "string"}
|
||||
},
|
||||
"required": ["location"]
|
||||
}
|
||||
}
|
||||
]
|
||||
|
||||
# Step 1: Request with tools (parallel_tool_calls=True allows multiple calls)
|
||||
response = litellm.responses(
|
||||
model="openai/gpt-4o",
|
||||
input=[{"role": "user", "content": "What's the weather in Paris and Tokyo?"}],
|
||||
tools=tools,
|
||||
parallel_tool_calls=True, # Defaults = True
|
||||
)
|
||||
|
||||
# Step 2: Execute tool calls and collect results
|
||||
tool_results = []
|
||||
for output in response.output:
|
||||
if output.type == "function_call":
|
||||
result = {"temperature": 15, "condition": "sunny"} # Your function logic here
|
||||
tool_results.append({
|
||||
"type": "function_call_output",
|
||||
"call_id": output.call_id,
|
||||
"output": json.dumps(result)
|
||||
})
|
||||
|
||||
# Step 3: Send results back
|
||||
final_response = litellm.responses(
|
||||
model="openai/gpt-4o",
|
||||
input=tool_results,
|
||||
tools=tools,
|
||||
)
|
||||
|
||||
print(final_response.output)
|
||||
```
|
||||
|
||||
Set `parallel_tool_calls=False` to ensure zero or one tool is called per turn. [More details](https://platform.openai.com/docs/guides/function-calling#parallel-function-calling).
|
||||
|
||||
## Free-form Function Calling
|
||||
|
||||
<Tabs>
|
||||
|
|
@ -633,7 +685,6 @@ display(styled_df)
|
|||
import litellm
|
||||
|
||||
response = litellm.responses(
|
||||
response = client.responses.create(
|
||||
model="gpt-5-mini",
|
||||
input="Please use the code_exec tool to calculate the area of a circle with radius equal to the number of 'r's in strawberry",
|
||||
text={"format": {"type": "text"}},
|
||||
|
|
|
|||
|
|
@ -8,7 +8,7 @@ https://stability.ai/
|
|||
| Description | Stability AI creates open AI models for image, video, audio, and 3D generation. Known for Stable Diffusion. |
|
||||
| Provider Route on LiteLLM | `stability/` |
|
||||
| Link to Provider Doc | [Stability AI API ↗](https://platform.stability.ai/docs/api-reference) |
|
||||
| Supported Operations | [`/images/generations`](#image-generation) |
|
||||
| Supported Operations | [`/images/generations`](#image-generation), [`/images/edits`](#image-editing) |
|
||||
|
||||
LiteLLM supports Stability AI Image Generation calls via the Stability AI REST API (not via Bedrock).
|
||||
|
||||
|
|
@ -169,13 +169,285 @@ Stability AI returns images in base64 format. The response is OpenAI-compatible:
|
|||
}
|
||||
```
|
||||
|
||||
## Comparing with Bedrock
|
||||
## Image Editing
|
||||
|
||||
Stability AI supports various image editing operations including inpainting, upscaling, outpainting, background removal, and more.
|
||||
|
||||
### Usage - LiteLLM Python SDK
|
||||
|
||||
#### Inpainting (Edit with Mask)
|
||||
|
||||
```python showLineNumbers
|
||||
from litellm import image_edit
|
||||
import os
|
||||
|
||||
os.environ['STABILITY_API_KEY'] = "your-api-key"
|
||||
|
||||
# Inpainting - edit specific areas using a mask
|
||||
response = image_edit(
|
||||
model="stability/stable-image-inpaint-v1:0",
|
||||
image=open("original_image.png", "rb"),
|
||||
mask=open("mask_image.png", "rb"),
|
||||
prompt="Add a beautiful sunset in the masked area",
|
||||
size="1024x1024",
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
#### Image Upscaling
|
||||
|
||||
```python showLineNumbers
|
||||
from litellm import image_edit
|
||||
import os
|
||||
|
||||
os.environ['STABILITY_API_KEY'] = "your-api-key"
|
||||
|
||||
# Conservative upscaling - preserves details
|
||||
response = image_edit(
|
||||
model="stability/stable-conservative-upscale-v1:0",
|
||||
image=open("low_res_image.png", "rb"),
|
||||
prompt="Upscale this image while preserving details",
|
||||
)
|
||||
|
||||
# Creative upscaling - adds creative details
|
||||
response = image_edit(
|
||||
model="stability/stable-creative-upscale-v1:0",
|
||||
image=open("low_res_image.png", "rb"),
|
||||
prompt="Upscale and enhance with creative details",
|
||||
creativity=0.3, # 0-0.35, higher = more creative
|
||||
)
|
||||
|
||||
# Fast upscaling - quick upscaling
|
||||
response = image_edit(
|
||||
model="stability/stable-fast-upscale-v1:0",
|
||||
image=open("low_res_image.png", "rb"),
|
||||
prompt="Quickly upscale this image",
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
#### Image Outpainting
|
||||
|
||||
```python showLineNumbers
|
||||
from litellm import image_edit
|
||||
import os
|
||||
|
||||
os.environ['STABILITY_API_KEY'] = "your-api-key"
|
||||
|
||||
# Extend image beyond its borders
|
||||
response = image_edit(
|
||||
model="stability/stable-outpaint-v1:0",
|
||||
image=open("original_image.png", "rb"),
|
||||
prompt="Extend this landscape with mountains",
|
||||
left=100, # Pixels to extend on the left
|
||||
right=100, # Pixels to extend on the right
|
||||
up=50, # Pixels to extend on top
|
||||
down=50, # Pixels to extend on bottom
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
#### Background Removal
|
||||
|
||||
```python showLineNumbers
|
||||
from litellm import image_edit
|
||||
import os
|
||||
|
||||
os.environ['STABILITY_API_KEY'] = "your-api-key"
|
||||
|
||||
# Remove background from image
|
||||
response = image_edit(
|
||||
model="stability/stable-image-remove-background-v1:0",
|
||||
image=open("portrait.png", "rb"),
|
||||
prompt="Remove the background",
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
#### Search and Replace
|
||||
|
||||
```python showLineNumbers
|
||||
from litellm import image_edit
|
||||
import os
|
||||
|
||||
os.environ['STABILITY_API_KEY'] = "your-api-key"
|
||||
|
||||
# Search and replace objects in image
|
||||
response = image_edit(
|
||||
model="stability/stable-image-search-replace-v1:0",
|
||||
image=open("scene.png", "rb"),
|
||||
prompt="A red sports car",
|
||||
search_prompt="blue sedan", # What to replace
|
||||
)
|
||||
|
||||
# Search and recolor
|
||||
response = image_edit(
|
||||
model="stability/stable-image-search-recolor-v1:0",
|
||||
image=open("scene.png", "rb"),
|
||||
prompt="Make it golden yellow",
|
||||
select_prompt="the car", # What to recolor
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
#### Image Control (Sketch/Structure)
|
||||
|
||||
```python showLineNumbers
|
||||
from litellm import image_edit
|
||||
import os
|
||||
|
||||
os.environ['STABILITY_API_KEY'] = "your-api-key"
|
||||
|
||||
# Control with sketch
|
||||
response = image_edit(
|
||||
model="stability/stable-image-control-sketch-v1:0",
|
||||
image=open("sketch.png", "rb"),
|
||||
prompt="Turn this sketch into a realistic photo",
|
||||
control_strength=0.7, # 0-1, higher = more control
|
||||
)
|
||||
|
||||
# Control with structure
|
||||
response = image_edit(
|
||||
model="stability/stable-image-control-structure-v1:0",
|
||||
image=open("structure_reference.png", "rb"),
|
||||
prompt="Generate image following this structure",
|
||||
control_strength=0.7,
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
#### Erase Objects
|
||||
|
||||
```python showLineNumbers
|
||||
from litellm import image_edit
|
||||
import os
|
||||
|
||||
os.environ['STABILITY_API_KEY'] = "your-api-key"
|
||||
|
||||
# Erase objects from image
|
||||
response = image_edit(
|
||||
model="stability/stable-image-erase-object-v1:0",
|
||||
image=open("scene.png", "rb"),
|
||||
mask=open("object_mask.png", "rb"), # Mask the object to erase
|
||||
prompt="Remove the object",
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
### Supported Image Edit Models
|
||||
|
||||
| Model Name | Function Call | Description |
|
||||
|------------|---------------|-------------|
|
||||
| stable-image-inpaint-v1:0 | `image_edit(model="stability/stable-image-inpaint-v1:0", ...)` | Inpainting with mask |
|
||||
| stable-conservative-upscale-v1:0 | `image_edit(model="stability/stable-conservative-upscale-v1:0", ...)` | Conservative upscaling |
|
||||
| stable-creative-upscale-v1:0 | `image_edit(model="stability/stable-creative-upscale-v1:0", ...)` | Creative upscaling |
|
||||
| stable-fast-upscale-v1:0 | `image_edit(model="stability/stable-fast-upscale-v1:0", ...)` | Fast upscaling |
|
||||
| stable-outpaint-v1:0 | `image_edit(model="stability/stable-outpaint-v1:0", ...)` | Extend image borders |
|
||||
| stable-image-remove-background-v1:0 | `image_edit(model="stability/stable-image-remove-background-v1:0", ...)` | Remove background |
|
||||
| stable-image-search-replace-v1:0 | `image_edit(model="stability/stable-image-search-replace-v1:0", ...)` | Search and replace objects |
|
||||
| stable-image-search-recolor-v1:0 | `image_edit(model="stability/stable-image-search-recolor-v1:0", ...)` | Search and recolor |
|
||||
| stable-image-control-sketch-v1:0 | `image_edit(model="stability/stable-image-control-sketch-v1:0", ...)` | Control with sketch |
|
||||
| stable-image-control-structure-v1:0 | `image_edit(model="stability/stable-image-control-structure-v1:0", ...)` | Control with structure |
|
||||
| stable-image-erase-object-v1:0 | `image_edit(model="stability/stable-image-erase-object-v1:0", ...)` | Erase objects |
|
||||
| stable-image-style-guide-v1:0 | `image_edit(model="stability/stable-image-style-guide-v1:0", ...)` | Apply style guide |
|
||||
| stable-style-transfer-v1:0 | `image_edit(model="stability/stable-style-transfer-v1:0", ...)` | Transfer style |
|
||||
|
||||
### Usage - LiteLLM Proxy Server
|
||||
|
||||
#### 1. Setup config.yaml
|
||||
|
||||
```yaml showLineNumbers
|
||||
model_list:
|
||||
- model_name: stability-inpaint
|
||||
litellm_params:
|
||||
model: stability/stable-image-inpaint-v1:0
|
||||
api_key: os.environ/STABILITY_API_KEY
|
||||
model_info:
|
||||
mode: image_edit
|
||||
|
||||
- model_name: stability-upscale
|
||||
litellm_params:
|
||||
model: stability/stable-conservative-upscale-v1:0
|
||||
api_key: os.environ/STABILITY_API_KEY
|
||||
model_info:
|
||||
mode: image_edit
|
||||
|
||||
general_settings:
|
||||
master_key: sk-1234
|
||||
```
|
||||
|
||||
#### 2. Start the proxy
|
||||
|
||||
```bash showLineNumbers
|
||||
litellm --config config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
#### 3. Test it
|
||||
|
||||
```bash showLineNumbers
|
||||
curl -X POST "http://0.0.0.0:4000/v1/images/edits" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-F "model=stability-inpaint" \
|
||||
-F "image=@original_image.png" \
|
||||
-F "mask=@mask_image.png" \
|
||||
-F "prompt=Add a beautiful garden in the masked area"
|
||||
```
|
||||
|
||||
## AWS Bedrock (Stability)
|
||||
|
||||
LiteLLM also supports Stability AI models via AWS Bedrock. This is useful if you're already using AWS infrastructure.
|
||||
|
||||
### Usage - Bedrock Stability
|
||||
|
||||
```python showLineNumbers
|
||||
from litellm import image_edit
|
||||
import os
|
||||
|
||||
# Set AWS credentials
|
||||
os.environ["AWS_ACCESS_KEY_ID"] = "your-access-key"
|
||||
os.environ["AWS_SECRET_ACCESS_KEY"] = "your-secret-key"
|
||||
os.environ["AWS_REGION_NAME"] = "us-east-1"
|
||||
|
||||
# Bedrock Stability inpainting
|
||||
response = image_edit(
|
||||
model="bedrock/us.stability.stable-image-inpaint-v1:0",
|
||||
image=open("original_image.png", "rb"),
|
||||
mask=open("mask_image.png", "rb"),
|
||||
prompt="Add flowers in the masked area",
|
||||
size="1024x1024",
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
### Supported Bedrock Stability Models
|
||||
|
||||
All Stability AI image edit models are available via Bedrock with the `bedrock/` prefix:
|
||||
|
||||
| Direct API Model | Bedrock Model | Description |
|
||||
|------------------|---------------|-------------|
|
||||
| stability/stable-image-inpaint-v1:0 | bedrock/us.stability.stable-image-inpaint-v1:0 | Inpainting |
|
||||
| stability/stable-conservative-upscale-v1:0 | bedrock/stability.stable-conservative-upscale-v1:0 | Conservative upscaling |
|
||||
| stability/stable-creative-upscale-v1:0 | bedrock/stability.stable-creative-upscale-v1:0 | Creative upscaling |
|
||||
| stability/stable-fast-upscale-v1:0 | bedrock/stability.stable-fast-upscale-v1:0 | Fast upscaling |
|
||||
| stability/stable-outpaint-v1:0 | bedrock/stability.stable-outpaint-v1:0 | Outpainting |
|
||||
| stability/stable-image-remove-background-v1:0 | bedrock/stability.stable-image-remove-background-v1:0 | Remove background |
|
||||
| stability/stable-image-search-replace-v1:0 | bedrock/stability.stable-image-search-replace-v1:0 | Search and replace |
|
||||
| stability/stable-image-search-recolor-v1:0 | bedrock/stability.stable-image-search-recolor-v1:0 | Search and recolor |
|
||||
| stability/stable-image-control-sketch-v1:0 | bedrock/stability.stable-image-control-sketch-v1:0 | Control with sketch |
|
||||
| stability/stable-image-control-structure-v1:0 | bedrock/stability.stable-image-control-structure-v1:0 | Control with structure |
|
||||
| stability/stable-image-erase-object-v1:0 | bedrock/stability.stable-image-erase-object-v1:0 | Erase objects |
|
||||
|
||||
**Note:** Bedrock model IDs may use `us.stability.*` or `stability.*` prefix depending on the region and model.
|
||||
|
||||
## Comparing Routes
|
||||
|
||||
LiteLLM supports Stability AI models via two routes:
|
||||
|
||||
| Route | Provider | Use Case |
|
||||
|-------|----------|----------|
|
||||
| `stability/` | Stability AI Direct API | Direct access, all latest models |
|
||||
| `bedrock/stability.*` | AWS Bedrock | AWS integration, enterprise features |
|
||||
| Route | Provider | Use Case | Image Generation | Image Editing |
|
||||
|-------|----------|----------|------------------|---------------|
|
||||
| `stability/` | Stability AI Direct API | Direct access, all latest models | ✅ | ✅ |
|
||||
| `bedrock/stability.*` | AWS Bedrock | AWS integration, enterprise features | ✅ | ✅ |
|
||||
|
||||
Use `stability/` for direct API access. Use `bedrock/stability.*` if you're already using AWS Bedrock.
|
||||
|
|
|
|||
|
|
@ -140,7 +140,7 @@ with open("document.pdf", "rb") as f:
|
|||
pdf_base64 = base64.b64encode(f.read()).decode()
|
||||
|
||||
response = litellm.ocr(
|
||||
model="vertex_ai/mistral-ocr-2505",
|
||||
model="vertex_ai/mistral-ocr-2505", # This doesn't work for deepseek
|
||||
document={
|
||||
"type": "document_url",
|
||||
"document_url": f"data:application/pdf;base64,{pdf_base64}"
|
||||
|
|
@ -219,7 +219,7 @@ print(f"Cost: ${response._hidden_params.get('response_cost', 0)}")
|
|||
## Important Notes
|
||||
|
||||
:::info URL Conversion
|
||||
Vertex AI OCR endpoints don't have internet access. LiteLLM automatically converts public URLs to base64 data URIs before sending requests to Vertex AI.
|
||||
Vertex AI Mistral OCR endpoints don't have internet access. LiteLLM automatically converts public URLs to base64 data URIs before sending requests to Vertex AI.
|
||||
:::
|
||||
|
||||
:::tip Regional Availability
|
||||
|
|
@ -227,11 +227,14 @@ Mistral OCR is available in multiple regions. Specify `vertex_location` to use a
|
|||
- `us-central1` (default)
|
||||
- `europe-west1`
|
||||
- `asia-southeast1`
|
||||
|
||||
Deepseek OCR is only available in global region.
|
||||
:::
|
||||
|
||||
## Supported Models
|
||||
|
||||
- `mistral-ocr-2505` - Latest Mistral OCR model on Vertex AI
|
||||
- `deepseek-ocr-maas` - Lates Deepseek OCR model on Vertex AI
|
||||
|
||||
Use the Vertex AI provider prefix: `vertex_ai/<model-name>`
|
||||
|
||||
|
|
|
|||
137
docs/my-website/docs/providers/xiaomi_mimo.md
Normal file
|
|
@ -0,0 +1,137 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Xiaomi MiMo
|
||||
https://platform.xiaomimimo.com/#/docs
|
||||
|
||||
:::tip
|
||||
|
||||
**We support ALL Xiaomi MiMo models, just set `model=xiaomi_mimo/<any-model-on-xiaomi-mimo>` as a prefix when sending litellm requests**
|
||||
|
||||
:::
|
||||
|
||||
## API Key
|
||||
```python
|
||||
# env variable
|
||||
os.environ['XIAOMI_MIMO_API_KEY']
|
||||
```
|
||||
|
||||
## Sample Usage
|
||||
```python
|
||||
from litellm import completion
|
||||
import os
|
||||
|
||||
os.environ['XIAOMI_MIMO_API_KEY'] = ""
|
||||
response = completion(
|
||||
model="xiaomi_mimo/mimo-v2-flash",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What's the weather like in Boston today in Fahrenheit?",
|
||||
}
|
||||
],
|
||||
max_tokens=1024,
|
||||
temperature=0.3,
|
||||
top_p=0.95,
|
||||
)
|
||||
print(response)
|
||||
```
|
||||
|
||||
## Sample Usage - Streaming
|
||||
```python
|
||||
from litellm import completion
|
||||
import os
|
||||
|
||||
os.environ['XIAOMI_MIMO_API_KEY'] = ""
|
||||
response = completion(
|
||||
model="xiaomi_mimo/mimo-v2-flash",
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": "What's the weather like in Boston today in Fahrenheit?",
|
||||
}
|
||||
],
|
||||
stream=True,
|
||||
max_tokens=1024,
|
||||
temperature=0.3,
|
||||
top_p=0.95,
|
||||
)
|
||||
|
||||
for chunk in response:
|
||||
print(chunk)
|
||||
```
|
||||
|
||||
|
||||
## Usage with LiteLLM Proxy Server
|
||||
|
||||
Here's how to call a Xiaomi MiMo model with the LiteLLM Proxy Server
|
||||
|
||||
1. Modify the config.yaml
|
||||
|
||||
```yaml
|
||||
model_list:
|
||||
- model_name: my-model
|
||||
litellm_params:
|
||||
model: xiaomi_mimo/<your-model-name> # add xiaomi_mimo/ prefix to route as Xiaomi MiMo provider
|
||||
api_key: api-key # api key to send your model
|
||||
```
|
||||
|
||||
|
||||
2. Start the proxy
|
||||
|
||||
```bash
|
||||
$ litellm --config /path/to/config.yaml
|
||||
```
|
||||
|
||||
3. Send Request to LiteLLM Proxy Server
|
||||
|
||||
<Tabs>
|
||||
|
||||
<TabItem value="openai" label="OpenAI Python v1.0.0+">
|
||||
|
||||
```python
|
||||
import openai
|
||||
client = openai.OpenAI(
|
||||
api_key="sk-1234", # pass litellm proxy key, if you're using virtual keys
|
||||
base_url="http://0.0.0.0:4000" # litellm-proxy-base url
|
||||
)
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="my-model",
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
)
|
||||
|
||||
print(response)
|
||||
```
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="curl" label="curl">
|
||||
|
||||
```shell
|
||||
curl --location 'http://0.0.0.0:4000/chat/completions' \
|
||||
--header 'Authorization: Bearer sk-1234' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{
|
||||
"model": "my-model",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "what llm are you"
|
||||
}
|
||||
],
|
||||
}'
|
||||
```
|
||||
</TabItem>
|
||||
|
||||
</Tabs>
|
||||
|
||||
## Supported Models
|
||||
|
||||
| Model Name | Usage |
|
||||
|------------|-------|
|
||||
| mimo-v2-flash | `completion(model="xiaomi_mimo/mimo-v2-flash", messages)` |
|
||||
|
|
@ -51,7 +51,7 @@ LiteLLM has two types of roles:
|
|||
| Role Name | Permissions |
|
||||
|-----------|-------------|
|
||||
| `org_admin` | Admin over a specific organization. Can create teams and users within their organization ✨ **Premium Feature** |
|
||||
| `team_admin` | Admin over a specific team. Can manage team members, update team settings, and create keys for their team. ✨ **Premium Feature** |
|
||||
| `team_admin` | Admin over a specific team. Can manage team members, update team member permissions, and create keys for their team. ✨ **Premium Feature** |
|
||||
|
||||
## What Can Each Role Do?
|
||||
|
||||
|
|
|
|||
|
|
@ -215,16 +215,16 @@ general_settings:
|
|||
alerting: ["slack"]
|
||||
alerting_threshold: 0.0001 # (Seconds) set an artificially low threshold for testing alerting
|
||||
alert_to_webhook_url: {
|
||||
"llm_exceptions": "https://hooks.slack.com/services/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",
|
||||
"llm_too_slow": "https://hooks.slack.com/services/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",
|
||||
"llm_requests_hanging": "https://hooks.slack.com/services/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",
|
||||
"budget_alerts": "https://hooks.slack.com/services/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",
|
||||
"db_exceptions": "https://hooks.slack.com/services/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",
|
||||
"daily_reports": "https://hooks.slack.com/services/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",
|
||||
"spend_reports": "https://hooks.slack.com/services/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",
|
||||
"cooldown_deployment": "https://hooks.slack.com/services/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",
|
||||
"new_model_added": "https://hooks.slack.com/services/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",
|
||||
"outage_alerts": "https://hooks.slack.com/services/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",
|
||||
"llm_exceptions": "example-slack-webhook-url",
|
||||
"llm_too_slow": "example-slack-webhook-url",
|
||||
"llm_requests_hanging": "example-slack-webhook-url",
|
||||
"budget_alerts": "example-slack-webhook-url",
|
||||
"db_exceptions": "example-slack-webhook-url",
|
||||
"daily_reports": "example-slack-webhook-url",
|
||||
"spend_reports": "example-slack-webhook-url",
|
||||
"cooldown_deployment": "example-slack-webhook-url",
|
||||
"new_model_added": "example-slack-webhook-url",
|
||||
"outage_alerts": "example-slack-webhook-url",
|
||||
}
|
||||
|
||||
litellm_settings:
|
||||
|
|
@ -399,7 +399,7 @@ curl -X GET --location 'http://0.0.0.0:4000/health/services?service=webhook' \
|
|||
{
|
||||
"spend": 1, # the spend for the 'event_group'
|
||||
"max_budget": 0, # the 'max_budget' set for the 'event_group'
|
||||
"token": "88dc28d0f030c55ed4ab77ed8faf098196cb1c05df778539800c9f1243fe6b4b",
|
||||
"token": "example-api-key-123",
|
||||
"user_id": "default_user_id",
|
||||
"team_id": null,
|
||||
"user_email": null,
|
||||
|
|
|
|||
|
|
@ -17,6 +17,7 @@ import Image from '@theme/IdealImage';
|
|||
| `async_pre_call_hook` | Modify incoming request before it's sent to model | Before the LLM API call is made |
|
||||
| `async_moderation_hook` | Run checks on input in parallel to LLM API call | In parallel with the LLM API call |
|
||||
| `async_post_call_success_hook` | Modify outgoing response (non-streaming) | After successful LLM API call, for non-streaming responses |
|
||||
| `async_post_call_failure_hook` | Transform error responses sent to clients | After failed LLM API call |
|
||||
| `async_post_call_streaming_hook` | Modify outgoing response (streaming) | After successful LLM API call, for streaming responses |
|
||||
|
||||
See a complete example with our [parallel request rate limiter](https://github.com/BerriAI/litellm/blob/main/litellm/proxy/hooks/parallel_request_limiter.py)
|
||||
|
|
@ -60,7 +61,21 @@ class MyCustomHandler(CustomLogger): # https://docs.litellm.ai/docs/observabilit
|
|||
original_exception: Exception,
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
traceback_str: Optional[str] = None,
|
||||
):
|
||||
) -> Optional[HTTPException]:
|
||||
"""
|
||||
Transform error responses sent to clients.
|
||||
|
||||
Return an HTTPException to replace the original error with a user-friendly message.
|
||||
Return None to use the original exception.
|
||||
|
||||
Example:
|
||||
if isinstance(original_exception, litellm.ContextWindowExceededError):
|
||||
return HTTPException(
|
||||
status_code=400,
|
||||
detail="Your prompt is too long. Please reduce the length and try again."
|
||||
)
|
||||
return None # Use original exception
|
||||
"""
|
||||
pass
|
||||
|
||||
async def async_post_call_success_hook(
|
||||
|
|
@ -339,3 +354,38 @@ curl --location 'http://0.0.0.0:4000/chat/completions' \
|
|||
"usage": {}
|
||||
}
|
||||
```
|
||||
|
||||
## Advanced - Transform Error Responses
|
||||
|
||||
Transform technical API errors into user-friendly messages using `async_post_call_failure_hook`. Return an `HTTPException` to replace the original error, or `None` to use the original exception.
|
||||
|
||||
```python
|
||||
from litellm.integrations.custom_logger import CustomLogger
|
||||
from fastapi import HTTPException
|
||||
from typing import Optional
|
||||
import litellm
|
||||
|
||||
class MyErrorTransformer(CustomLogger):
|
||||
async def async_post_call_failure_hook(
|
||||
self,
|
||||
request_data: dict,
|
||||
original_exception: Exception,
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
traceback_str: Optional[str] = None,
|
||||
) -> Optional[HTTPException]:
|
||||
if isinstance(original_exception, litellm.ContextWindowExceededError):
|
||||
return HTTPException(
|
||||
status_code=400,
|
||||
detail="Your prompt is too long. Please reduce the length and try again."
|
||||
)
|
||||
if isinstance(original_exception, litellm.RateLimitError):
|
||||
return HTTPException(
|
||||
status_code=429,
|
||||
detail="Rate limit exceeded. Please try again in a moment."
|
||||
)
|
||||
return None # Use original exception
|
||||
|
||||
proxy_handler_instance = MyErrorTransformer()
|
||||
```
|
||||
|
||||
**Result:** Clients receive `"Your prompt is too long..."` instead of `"ContextWindowExceededError: Prompt exceeds context window"`.
|
||||
|
|
|
|||
|
|
@ -346,6 +346,7 @@ router_settings:
|
|||
| optional_pre_call_checks | List[str] | List of pre-call checks to add to the router. Currently supported: 'router_budget_limiting', 'prompt_caching' |
|
||||
| ignore_invalid_deployments | boolean | If true, ignores invalid deployments. Default for proxy is True - to prevent invalid models from blocking other models from being loaded. |
|
||||
| search_tools | List[SearchToolTypedDict] | List of search tool configurations for Search API integration. Each tool specifies a search_tool_name and litellm_params with search_provider, api_key, api_base, etc. [Further Docs](../search.md) |
|
||||
| guardrail_list | List[GuardrailTypedDict] | List of guardrail configurations for guardrail load balancing. Enables load balancing across multiple guardrail deployments with the same guardrail_name. [Further Docs](./guardrails/guardrail_load_balancing.md) |
|
||||
|
||||
|
||||
### environment variables - Reference
|
||||
|
|
@ -413,6 +414,12 @@ router_settings:
|
|||
| AZURE_FEDERATED_TOKEN_FILE | File path to Azure federated token
|
||||
| AZURE_FILE_SEARCH_COST_PER_GB_PER_DAY | Cost per GB per day for Azure File Search service
|
||||
| AZURE_SCOPE | For EntraID Auth, Scope for Azure services, defaults to "https://cognitiveservices.azure.com/.default"
|
||||
| AZURE_SENTINEL_DCR_IMMUTABLE_ID | Immutable ID of the Data Collection Rule for Azure Sentinel logging
|
||||
| AZURE_SENTINEL_STREAM_NAME | Stream name for Azure Sentinel logging
|
||||
| AZURE_SENTINEL_CLIENT_SECRET | Client secret for Azure Sentinel authentication
|
||||
| AZURE_SENTINEL_ENDPOINT | Endpoint for Azure Sentinel logging
|
||||
| AZURE_SENTINEL_TENANT_ID | Tenant ID for Azure Sentinel authentication
|
||||
| AZURE_SENTINEL_CLIENT_ID | Client ID for Azure Sentinel authentication
|
||||
| AZURE_KEY_VAULT_URI | URI for Azure Key Vault
|
||||
| AZURE_OPERATION_POLLING_TIMEOUT | Timeout in seconds for Azure operation polling
|
||||
| AZURE_STORAGE_ACCOUNT_KEY | The Azure Storage Account Key to use for Authentication to Azure Blob Storage logging
|
||||
|
|
@ -541,10 +548,14 @@ router_settings:
|
|||
| DOCS_TITLE | Title of the documentation pages
|
||||
| DOCS_URL | The path to the Swagger API documentation. **By default this is "/"**
|
||||
| EMAIL_LOGO_URL | URL for the logo used in emails
|
||||
| EMAIL_BUDGET_ALERT_TTL | Time-to-live for email budget alerts in seconds
|
||||
| EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE | Maximum spend percentage for triggering email budget alerts
|
||||
| EMAIL_SUPPORT_CONTACT | Support contact email address
|
||||
| EMAIL_SIGNATURE | Custom HTML footer/signature for all emails. Can include HTML tags for formatting and links.
|
||||
| EMAIL_SUBJECT_INVITATION | Custom subject template for invitation emails.
|
||||
| EMAIL_SUBJECT_KEY_CREATED | Custom subject template for key creation emails.
|
||||
| EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE | Percentage of max budget that triggers alerts (as decimal: 0.8 = 80%). Default is 0.8
|
||||
| EMAIL_BUDGET_ALERT_TTL | Time-to-live for budget alert deduplication in seconds. Default is 86400 (24 hours)
|
||||
| ENKRYPTAI_API_BASE | Base URL for EnkryptAI Guardrails API. **Default is https://api.enkryptai.com**
|
||||
| ENKRYPTAI_API_KEY | API key for EnkryptAI Guardrails service
|
||||
| EXPERIMENTAL_MULTI_INSTANCE_RATE_LIMITING | Flag to enable new multi-instance rate limiting. **Default is False**
|
||||
|
|
@ -596,6 +607,8 @@ router_settings:
|
|||
| GREENSCALE_ENDPOINT | Endpoint URL for Greenscale service
|
||||
| GRAYSWAN_API_BASE | Base URL for GraySwan API. Default is https://api.grayswan.ai
|
||||
| GRAYSWAN_API_KEY | API key for GraySwan Cygnal service
|
||||
| GRAYSWAN_REASONING_MODE | Reasoning mode for GraySwan guardrail
|
||||
| GRAYSWAN_VIOLATION_THRESHOLD | Violation threshold for GraySwan guardrail
|
||||
| GOOGLE_APPLICATION_CREDENTIALS | Path to Google Cloud credentials JSON file
|
||||
| GOOGLE_CLIENT_ID | Client ID for Google OAuth
|
||||
| GOOGLE_CLIENT_SECRET | Client secret for Google OAuth
|
||||
|
|
@ -825,6 +838,7 @@ router_settings:
|
|||
| SMTP_TLS | Flag to enable or disable TLS for SMTP connections
|
||||
| SMTP_USERNAME | Username for SMTP authentication (do not set if SMTP does not require auth)
|
||||
| SENDGRID_API_KEY | API key for SendGrid email service
|
||||
| RESEND_API_KEY | API key for Resend email service
|
||||
| SENDGRID_SENDER_EMAIL | Email address used as the sender in SendGrid email transactions
|
||||
| SPEND_LOGS_URL | URL for retrieving spend logs
|
||||
| SPEND_LOG_CLEANUP_BATCH_SIZE | Number of logs deleted per batch during cleanup. Default is 1000
|
||||
|
|
|
|||
|
|
@ -722,7 +722,7 @@ curl -X GET 'http://localhost:4000/global/spend/report?start_date=2024-04-01&end
|
|||
```shell
|
||||
[
|
||||
{
|
||||
"api_key": "88dc28d0f030c55ed4ab77ed8faf098196cb1c05df778539800c9f1243fe6b4b",
|
||||
"api_key": "example-api-key-123",
|
||||
"total_cost": 0.3201286305151999,
|
||||
"total_input_tokens": 36.0,
|
||||
"total_output_tokens": 1593.0,
|
||||
|
|
@ -766,7 +766,7 @@ curl -X GET 'http://localhost:4000/global/spend/report?start_date=2024-04-01&end
|
|||
```shell
|
||||
[
|
||||
{
|
||||
"api_key": "88dc28d0f030c55ed4ab77ed8faf098196cb1c05df778539800c9f1243fe6b4b",
|
||||
"api_key": "example-api-key-123",
|
||||
"total_cost": 0.00013132,
|
||||
"total_input_tokens": 105.0,
|
||||
"total_output_tokens": 872.0,
|
||||
|
|
@ -1151,7 +1151,7 @@ curl -X GET "http://0.0.0.0:4000/spend/logs?request_id=<your-call-id" \ # e.g.:
|
|||
"request_id": "chatcmpl-9ZKMURhVYSi9D6r6PJ9vLcayIK0Vm",
|
||||
"call_type": "acompletion",
|
||||
"metadata": {
|
||||
"user_api_key": "88dc28d0f030c55ed4ab77ed8faf098196cb1c05df778539800c9f1243fe6b4b",
|
||||
"user_api_key": "example-api-key-123",
|
||||
"user_api_key_alias": null,
|
||||
"spend_logs_metadata": { # 👈 LOGGED CUSTOM METADATA
|
||||
"hello": "world"
|
||||
|
|
|
|||
|
|
@ -9,6 +9,7 @@ You can now override the default api key auth.
|
|||
Make sure the response type follows the `UserAPIKeyAuth` pydantic object. This is used by for logging usage specific to that user key.
|
||||
|
||||
```python
|
||||
from fastapi import Request
|
||||
from litellm.proxy._types import UserAPIKeyAuth
|
||||
|
||||
async def user_api_key_auth(request: Request, api_key: str) -> UserAPIKeyAuth:
|
||||
|
|
@ -114,6 +115,29 @@ UserAPIKeyAuth(
|
|||
)
|
||||
```
|
||||
|
||||
### Object Permission Example (MCP, agents, etc.)
|
||||
|
||||
```python
|
||||
from litellm.proxy._experimental.mcp_server.mcp_server_manager import (
|
||||
global_mcp_server_manager,
|
||||
)
|
||||
|
||||
def _server_id(name: str) -> str:
|
||||
server = global_mcp_server_manager.get_mcp_server_by_name(name)
|
||||
if not server:
|
||||
raise ValueError(f"Unknown MCP server '{name}'")
|
||||
return server.server_id
|
||||
|
||||
object_permission = LiteLLM_ObjectPermissionTable(
|
||||
mcp_servers=[_server_id("deepwiki"), _server_id("everything")], # MCP servers this key is allowed to use
|
||||
mcp_tool_permissions={"deepwiki": ["search", "read_doc"]}, # optional per-server tool allow-list
|
||||
)
|
||||
|
||||
UserAPIKeyAuth(
|
||||
object_permission=object_permission,
|
||||
)
|
||||
```
|
||||
|
||||
### Advanced Configuration
|
||||
```python
|
||||
UserAPIKeyAuth(
|
||||
|
|
@ -139,6 +163,7 @@ UserAPIKeyAuth(
|
|||
### Complete Example
|
||||
|
||||
```python
|
||||
from fastapi import Request
|
||||
from datetime import datetime, timedelta
|
||||
from litellm.proxy._types import UserAPIKeyAuth, LitellmUserRoles
|
||||
|
||||
|
|
@ -333,4 +358,4 @@ async def user_api_key_auth(
|
|||
except Exception:
|
||||
raise Exception("Invalid API key")
|
||||
|
||||
```
|
||||
```
|
||||
|
|
|
|||
|
|
@ -103,7 +103,7 @@ Expected Response
|
|||
{
|
||||
"spend": 0.0011120000000000001, # 👈 SPEND
|
||||
"max_budget": null,
|
||||
"token": "88dc28d0f030c55ed4ab77ed8faf098196cb1c05df778539800c9f1243fe6b4b",
|
||||
"token": "example-api-key-123",
|
||||
"customer_id": "krrish12", # 👈 CUSTOMER ID
|
||||
"user_id": null,
|
||||
"team_id": null,
|
||||
|
|
|
|||
|
|
@ -94,6 +94,35 @@ On the LiteLLM Proxy UI, go to users > create a new user.
|
|||
|
||||
After creating a new user, they will receive an email invite a the email you specified when creating the user.
|
||||
|
||||
### 3. Configure Budget Alerts (Optional)
|
||||
|
||||
Enable budget alert emails by adding "email" to the `alerts` list in your proxy configuration:
|
||||
|
||||
```yaml showLineNumbers title="proxy_config.yaml"
|
||||
general_settings:
|
||||
alerts: ["email"]
|
||||
```
|
||||
|
||||
#### Budget Alert Types
|
||||
|
||||
**Soft Budget Alerts**: Automatically triggered when a key exceeds its soft budget limit. These alerts help you monitor spending before reaching critical thresholds.
|
||||
|
||||
**Max Budget Alerts**: Automatically triggered when a key reaches a specified percentage of its maximum budget (default: 80%). These alerts warn you when you're approaching budget exhaustion.
|
||||
|
||||
Both alert types send a maximum of one email per 24-hour period to prevent spam.
|
||||
|
||||
#### Configuration Options
|
||||
|
||||
Customize budget alert behavior using these environment variables:
|
||||
|
||||
```yaml showLineNumbers title=".env"
|
||||
# Percentage of max budget that triggers alerts (as decimal: 0.8 = 80%)
|
||||
EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE=0.8
|
||||
|
||||
# Time-to-live for alert deduplication in seconds (default: 24 hours)
|
||||
EMAIL_BUDGET_ALERT_TTL=86400
|
||||
```
|
||||
|
||||
## Email Templates
|
||||
|
||||
|
||||
|
|
|
|||
|
|
@ -0,0 +1,351 @@
|
|||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
# Guardrail Load Balancing
|
||||
|
||||
Load balance guardrail requests across multiple guardrail deployments. This is useful when you have rate limits on guardrail providers (e.g., AWS Bedrock Guardrails) and want to distribute requests across multiple accounts or regions.
|
||||
|
||||
## How It Works
|
||||
|
||||
```mermaid
|
||||
flowchart LR
|
||||
subgraph LiteLLM Gateway
|
||||
Router[Router]
|
||||
G1[Guardrail Instance A]
|
||||
G2[Guardrail Instance B]
|
||||
G3[Guardrail Instance N]
|
||||
end
|
||||
|
||||
Client[Client Request] --> Router
|
||||
Router -->|Round Robin / Weighted| G1
|
||||
Router -->|Round Robin / Weighted| G2
|
||||
Router -->|Round Robin / Weighted| G3
|
||||
|
||||
G1 --> AWS1[AWS Account 1]
|
||||
G2 --> AWS2[AWS Account 2]
|
||||
G3 --> AWSN[AWS Account N]
|
||||
```
|
||||
|
||||
When you define multiple guardrails with the **same `guardrail_name`**, LiteLLM automatically load balances requests across them using the router's load balancing strategy.
|
||||
|
||||
## Why Use Guardrail Load Balancing?
|
||||
|
||||
| Use Case | Benefit |
|
||||
|----------|---------|
|
||||
| **AWS Bedrock Rate Limits** | Bedrock Guardrails have per-account rate limits. Distribute across multiple AWS accounts to increase throughput |
|
||||
| **Multi-Region Redundancy** | Deploy guardrails across regions for failover and lower latency |
|
||||
| **Cost Optimization** | Spread usage across accounts with different pricing tiers or credits |
|
||||
| **A/B Testing** | Test different guardrail configurations with weighted distribution |
|
||||
|
||||
## Quick Start
|
||||
|
||||
### 1. Define Multiple Guardrails with Same Name
|
||||
|
||||
Define multiple guardrail entries with the **same `guardrail_name`** but different configurations:
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="bedrock" label="Bedrock Guardrails">
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: openai/gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
guardrails:
|
||||
# First Bedrock guardrail - AWS Account 1
|
||||
- guardrail_name: "content-filter"
|
||||
litellm_params:
|
||||
guardrail: bedrock/guardrail
|
||||
mode: "pre_call"
|
||||
guardrailIdentifier: "abc123"
|
||||
guardrailVersion: "1"
|
||||
aws_access_key_id: os.environ/AWS_ACCESS_KEY_ID_1
|
||||
aws_secret_access_key: os.environ/AWS_SECRET_ACCESS_KEY_1
|
||||
aws_region_name: "us-east-1"
|
||||
|
||||
# Second Bedrock guardrail - AWS Account 2
|
||||
- guardrail_name: "content-filter"
|
||||
litellm_params:
|
||||
guardrail: bedrock/guardrail
|
||||
mode: "pre_call"
|
||||
guardrailIdentifier: "def456"
|
||||
guardrailVersion: "1"
|
||||
aws_access_key_id: os.environ/AWS_ACCESS_KEY_ID_2
|
||||
aws_secret_access_key: os.environ/AWS_SECRET_ACCESS_KEY_2
|
||||
aws_region_name: "us-west-2"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="custom" label="Custom Guardrails">
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: openai/gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
guardrails:
|
||||
# First custom guardrail instance
|
||||
- guardrail_name: "pii-filter"
|
||||
litellm_params:
|
||||
guardrail: custom_guardrail.PIIFilterA
|
||||
mode: "pre_call"
|
||||
|
||||
# Second custom guardrail instance
|
||||
- guardrail_name: "pii-filter"
|
||||
litellm_params:
|
||||
guardrail: custom_guardrail.PIIFilterB
|
||||
mode: "pre_call"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="aporia" label="Aporia Guardrails">
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: openai/gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
guardrails:
|
||||
# First Aporia instance
|
||||
- guardrail_name: "toxicity-filter"
|
||||
litellm_params:
|
||||
guardrail: aporia
|
||||
mode: "pre_call"
|
||||
api_key: os.environ/APORIA_API_KEY_1
|
||||
api_base: os.environ/APORIA_API_BASE_1
|
||||
|
||||
# Second Aporia instance
|
||||
- guardrail_name: "toxicity-filter"
|
||||
litellm_params:
|
||||
guardrail: aporia
|
||||
mode: "pre_call"
|
||||
api_key: os.environ/APORIA_API_KEY_2
|
||||
api_base: os.environ/APORIA_API_BASE_2
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### 2. Start LiteLLM Gateway
|
||||
|
||||
```bash showLineNumbers title="Start proxy"
|
||||
litellm --config config.yaml --detailed_debug
|
||||
```
|
||||
|
||||
### 3. Make Requests
|
||||
|
||||
Requests using the guardrail will be automatically load balanced:
|
||||
|
||||
```bash showLineNumbers title="Test request"
|
||||
curl -X POST http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "gpt-4",
|
||||
"messages": [{"role": "user", "content": "Hello, how are you?"}],
|
||||
"guardrails": ["content-filter"]
|
||||
}'
|
||||
```
|
||||
|
||||
## Weighted Load Balancing
|
||||
|
||||
Assign weights to distribute traffic unevenly across guardrail instances:
|
||||
|
||||
```yaml showLineNumbers title="config.yaml - Weighted distribution"
|
||||
guardrails:
|
||||
# 80% of traffic
|
||||
- guardrail_name: "content-filter"
|
||||
litellm_params:
|
||||
guardrail: bedrock/guardrail
|
||||
mode: "pre_call"
|
||||
guardrailIdentifier: "primary-guard"
|
||||
guardrailVersion: "1"
|
||||
weight: 8 # Higher weight = more traffic
|
||||
|
||||
# 20% of traffic
|
||||
- guardrail_name: "content-filter"
|
||||
litellm_params:
|
||||
guardrail: bedrock/guardrail
|
||||
mode: "pre_call"
|
||||
guardrailIdentifier: "secondary-guard"
|
||||
guardrailVersion: "1"
|
||||
weight: 2 # Lower weight = less traffic
|
||||
```
|
||||
|
||||
## Bedrock Guardrails - Multi-Account Setup
|
||||
|
||||
AWS Bedrock Guardrails have rate limits per account. Here's how to set up load balancing across multiple AWS accounts:
|
||||
|
||||
### Architecture
|
||||
|
||||
```mermaid
|
||||
flowchart TB
|
||||
subgraph LiteLLM["LiteLLM Gateway"]
|
||||
LB[Load Balancer]
|
||||
end
|
||||
|
||||
subgraph AWS1["AWS Account 1 (us-east-1)"]
|
||||
BG1[Bedrock Guardrail]
|
||||
end
|
||||
|
||||
subgraph AWS2["AWS Account 2 (us-west-2)"]
|
||||
BG2[Bedrock Guardrail]
|
||||
end
|
||||
|
||||
subgraph AWS3["AWS Account 3 (eu-west-1)"]
|
||||
BG3[Bedrock Guardrail]
|
||||
end
|
||||
|
||||
Client[Client] --> LiteLLM
|
||||
LB --> BG1
|
||||
LB --> BG2
|
||||
LB --> BG3
|
||||
```
|
||||
|
||||
### Configuration
|
||||
|
||||
```yaml showLineNumbers title="config.yaml - Multi-account Bedrock"
|
||||
model_list:
|
||||
- model_name: claude-3
|
||||
litellm_params:
|
||||
model: bedrock/anthropic.claude-3-sonnet-20240229-v1:0
|
||||
|
||||
guardrails:
|
||||
# AWS Account 1 - US East
|
||||
- guardrail_name: "bedrock-content-filter"
|
||||
litellm_params:
|
||||
guardrail: bedrock/guardrail
|
||||
mode: "during_call"
|
||||
guardrailIdentifier: "guard-us-east"
|
||||
guardrailVersion: "DRAFT"
|
||||
aws_access_key_id: os.environ/AWS_ACCESS_KEY_1
|
||||
aws_secret_access_key: os.environ/AWS_SECRET_KEY_1
|
||||
aws_region_name: "us-east-1"
|
||||
|
||||
# AWS Account 2 - US West
|
||||
- guardrail_name: "bedrock-content-filter"
|
||||
litellm_params:
|
||||
guardrail: bedrock/guardrail
|
||||
mode: "during_call"
|
||||
guardrailIdentifier: "guard-us-west"
|
||||
guardrailVersion: "DRAFT"
|
||||
aws_access_key_id: os.environ/AWS_ACCESS_KEY_2
|
||||
aws_secret_access_key: os.environ/AWS_SECRET_KEY_2
|
||||
aws_region_name: "us-west-2"
|
||||
|
||||
# AWS Account 3 - EU West
|
||||
- guardrail_name: "bedrock-content-filter"
|
||||
litellm_params:
|
||||
guardrail: bedrock/guardrail
|
||||
mode: "during_call"
|
||||
guardrailIdentifier: "guard-eu-west"
|
||||
guardrailVersion: "DRAFT"
|
||||
aws_access_key_id: os.environ/AWS_ACCESS_KEY_3
|
||||
aws_secret_access_key: os.environ/AWS_SECRET_KEY_3
|
||||
aws_region_name: "eu-west-1"
|
||||
```
|
||||
|
||||
### Test Multi-Account Setup
|
||||
|
||||
```bash showLineNumbers title="Run multiple requests to verify load balancing"
|
||||
# Run 10 requests - they will be distributed across accounts
|
||||
for i in {1..10}; do
|
||||
curl -s -X POST http://localhost:4000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-d '{
|
||||
"model": "claude-3",
|
||||
"messages": [{"role": "user", "content": "Hello"}],
|
||||
"guardrails": ["bedrock-content-filter"]
|
||||
}' &
|
||||
done
|
||||
wait
|
||||
```
|
||||
|
||||
Check proxy logs to verify requests are distributed across different AWS accounts.
|
||||
|
||||
## Custom Guardrails Example
|
||||
|
||||
Create two custom guardrail classes for load balancing:
|
||||
|
||||
```python showLineNumbers title="custom_guardrail.py"
|
||||
from litellm.integrations.custom_guardrail import CustomGuardrail
|
||||
from litellm.proxy._types import UserAPIKeyAuth
|
||||
from litellm.caching.caching import DualCache
|
||||
|
||||
|
||||
class PIIFilterA(CustomGuardrail):
|
||||
"""PII Filter Instance A"""
|
||||
|
||||
async def async_pre_call_hook(
|
||||
self,
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
cache: DualCache,
|
||||
data: dict,
|
||||
call_type: str,
|
||||
):
|
||||
print("PIIFilterA processing request")
|
||||
# Your PII filtering logic here
|
||||
return data
|
||||
|
||||
|
||||
class PIIFilterB(CustomGuardrail):
|
||||
"""PII Filter Instance B"""
|
||||
|
||||
async def async_pre_call_hook(
|
||||
self,
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
cache: DualCache,
|
||||
data: dict,
|
||||
call_type: str,
|
||||
):
|
||||
print("PIIFilterB processing request")
|
||||
# Your PII filtering logic here
|
||||
return data
|
||||
```
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
guardrails:
|
||||
- guardrail_name: "pii-filter"
|
||||
litellm_params:
|
||||
guardrail: custom_guardrail.PIIFilterA
|
||||
mode: "pre_call"
|
||||
|
||||
- guardrail_name: "pii-filter"
|
||||
litellm_params:
|
||||
guardrail: custom_guardrail.PIIFilterB
|
||||
mode: "pre_call"
|
||||
```
|
||||
|
||||
## Verifying Load Balancing
|
||||
|
||||
Enable detailed debug logging to verify load balancing is working:
|
||||
|
||||
```bash showLineNumbers title="Start with debug logging"
|
||||
litellm --config config.yaml --detailed_debug
|
||||
```
|
||||
|
||||
You should see logs indicating which guardrail instance is selected:
|
||||
|
||||
```
|
||||
Selected guardrail deployment: bedrock/guardrail (guard-us-east)
|
||||
Selected guardrail deployment: bedrock/guardrail (guard-us-west)
|
||||
Selected guardrail deployment: bedrock/guardrail (guard-eu-west)
|
||||
...
|
||||
```
|
||||
|
||||
## Related
|
||||
|
||||
- [Guardrails Quick Start](./quick_start.md)
|
||||
- [Bedrock Guardrails](./bedrock.md)
|
||||
- [Custom Guardrails](./custom_guardrail.md)
|
||||
- [Load Balancing for LLM Calls](../load_balancing.md)
|
||||
|
||||
|
|
@ -29,6 +29,13 @@ guardrails:
|
|||
mode: "pre_call"
|
||||
api_key: os.environ/LAKERA_API_KEY
|
||||
api_base: os.environ/LAKERA_API_BASE
|
||||
- guardrail_name: "lakera-monitor"
|
||||
litellm_params:
|
||||
guardrail: lakera_v2
|
||||
mode: "pre_call"
|
||||
on_flagged: "monitor" # Log violations but don't block
|
||||
api_key: os.environ/LAKERA_API_KEY
|
||||
api_base: os.environ/LAKERA_API_BASE
|
||||
|
||||
```
|
||||
|
||||
|
|
@ -144,6 +151,7 @@ guardrails:
|
|||
# breakdown: Optional[bool] = True,
|
||||
# metadata: Optional[Dict] = None,
|
||||
# dev_info: Optional[bool] = True,
|
||||
# on_flagged: Optional[str] = "block", # "block" or "monitor"
|
||||
```
|
||||
|
||||
- `api_base`: (Optional[str]) The base of the Lakera integration. Defaults to `https://api.lakera.ai`
|
||||
|
|
@ -153,3 +161,6 @@ guardrails:
|
|||
- `breakdown`: (Optional[bool]) When true the response will return a breakdown list of the detectors that were run, as defined in the policy, and whether each of them detected something or not.
|
||||
- `metadata`: (Optional[Dict]) Metadata tags can be attached to screening requests as an object that can contain any arbitrary key-value pairs.
|
||||
- `dev_info`: (Optional[bool]) When true the response will return an object with developer information about the build of Lakera Guard.
|
||||
- `on_flagged`: (Optional[str]) Action to take when content is flagged. Defaults to `"block"`.
|
||||
- `"block"`: Raises an HTTP 400 exception when violations are detected (default behavior)
|
||||
- `"monitor"`: Logs violations but allows the request to proceed. Useful for tuning security policies without blocking legitimate requests.
|
||||
|
|
|
|||
|
|
@ -3,10 +3,12 @@ import TabItem from '@theme/TabItem';
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
|
||||
# LiteLLM Content Filter
|
||||
# LiteLLM Content Filter (Built-in Guardrails)
|
||||
|
||||
**Built-in guardrail** for detecting and filtering sensitive information using regex patterns and keyword matching. No external dependencies required.
|
||||
|
||||
**When to use?** Good for cases which do not require an ML model to detect sensitive information.
|
||||
|
||||
## Overview
|
||||
|
||||
| Property | Details |
|
||||
|
|
@ -56,6 +58,44 @@ Test examples:
|
|||
|
||||
### Step 1: Define Guardrails in config.yaml
|
||||
|
||||
<Tabs>
|
||||
<TabItem label="Harmful Content Detection" value="harmful">
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-3.5-turbo
|
||||
litellm_params:
|
||||
model: openai/gpt-3.5-turbo
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
guardrails:
|
||||
- guardrail_name: "harmful-content-filter"
|
||||
litellm_params:
|
||||
guardrail: litellm_content_filter
|
||||
mode: "pre_call"
|
||||
|
||||
# Enable harmful content categories
|
||||
categories:
|
||||
- category: "harmful_self_harm"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "medium"
|
||||
|
||||
- category: "harmful_violence"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "medium"
|
||||
|
||||
- category: "harmful_illegal_weapons"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "medium"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem label="PII Protection" value="pii">
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-3.5-turbo
|
||||
|
|
@ -86,6 +126,48 @@ guardrails:
|
|||
description: "Sensitive internal information"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem label="Combined" value="combined">
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-3.5-turbo
|
||||
litellm_params:
|
||||
model: openai/gpt-3.5-turbo
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
guardrails:
|
||||
- guardrail_name: "comprehensive-filter"
|
||||
litellm_params:
|
||||
guardrail: litellm_content_filter
|
||||
mode: "pre_call"
|
||||
|
||||
# Harmful content categories
|
||||
categories:
|
||||
- category: "harmful_violence"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "high"
|
||||
|
||||
# PII patterns
|
||||
patterns:
|
||||
- pattern_type: "prebuilt"
|
||||
pattern_name: "us_ssn"
|
||||
action: "BLOCK"
|
||||
- pattern_type: "prebuilt"
|
||||
pattern_name: "email"
|
||||
action: "MASK"
|
||||
|
||||
# Custom keywords
|
||||
blocked_words:
|
||||
- keyword: "confidential"
|
||||
action: "BLOCK"
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
### Step 2: Start LiteLLM Gateway
|
||||
|
||||
```shell
|
||||
|
|
@ -175,7 +257,7 @@ Contact me at [EMAIL_REDACTED]
|
|||
| `amex` | American Express cards | `3782-822463-10005` |
|
||||
| `aws_access_key` | AWS access keys | `AKIAIOSFODNN7EXAMPLE` |
|
||||
| `aws_secret_key` | AWS secret keys | `wJalrXUtnFEMI/K7MDENG/bPxRfi...` |
|
||||
| `github_token` | GitHub tokens | `ghp_16C7e42F292c6912E7710c838347Ae178B4a` |
|
||||
| `github_token` | GitHub tokens | `example-github-token-123` |
|
||||
|
||||
### Using Prebuilt Patterns
|
||||
|
||||
|
|
@ -310,6 +392,85 @@ for chunk in response:
|
|||
# Emails automatically masked in real-time
|
||||
```
|
||||
|
||||
## Image Content Filtering
|
||||
|
||||
Content filter can analyze images by generating descriptions and applying filters to the text descriptions.
|
||||
|
||||
:::warning
|
||||
|
||||
This can introduce significant latency to the request - depending on the speed of the vision-capable model.
|
||||
|
||||
This is because, each request containing images will be sent to the vision-capable model to generate a description.
|
||||
|
||||
:::
|
||||
|
||||
### Configuration
|
||||
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4-vision
|
||||
litellm_params:
|
||||
model: openai/gpt-4-vision-preview
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
guardrails:
|
||||
- guardrail_name: "image-filter"
|
||||
litellm_params:
|
||||
guardrail: litellm_content_filter
|
||||
mode: "pre_call"
|
||||
image_model: "gpt-4-vision" # value is `model_name` of the vision-capable model
|
||||
|
||||
# Apply same filters to image descriptions
|
||||
categories:
|
||||
- category: "harmful_violence"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "medium"
|
||||
|
||||
patterns:
|
||||
- pattern_type: "prebuilt"
|
||||
pattern_name: "email"
|
||||
action: "MASK"
|
||||
```
|
||||
|
||||
### How It Works
|
||||
|
||||
1. Image is sent to the vision model to generate a text description
|
||||
2. Content filters are applied to the description
|
||||
3. If harmful content is detected, request is blocked with context about the image
|
||||
|
||||
**Example:**
|
||||
|
||||
```python
|
||||
import openai
|
||||
|
||||
client = openai.OpenAI(
|
||||
api_key="sk-1234",
|
||||
base_url="http://localhost:4000"
|
||||
)
|
||||
|
||||
response = client.chat.completions.create(
|
||||
model="gpt-4-vision",
|
||||
messages=[{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"type": "text", "text": "What's in this image?"},
|
||||
{"type": "image_url", "image_url": {"url": "https://example.com/image.jpg"}}
|
||||
]
|
||||
}],
|
||||
extra_body={"guardrails": ["image-filter"]}
|
||||
)
|
||||
```
|
||||
|
||||
If the image description contains filtered content, you'll get:
|
||||
|
||||
```json
|
||||
{
|
||||
"error": "Content blocked: harmful_violence category keyword 'weapon' detected (severity: high) (Image description): The image shows..."
|
||||
}
|
||||
```
|
||||
|
||||
## Customizing Redaction Tags
|
||||
|
||||
When using the `MASK` action, sensitive content is replaced with redaction tags. You can customize how these tags appear.
|
||||
|
|
@ -363,9 +524,171 @@ Output: "Email ***EMAIL***, SSN ***US_SSN***, ***REDACTED*** data"
|
|||
- Pattern names are automatically uppercased (e.g., `email` → `EMAIL`)
|
||||
- `keyword_redaction_tag` is a fixed string (no placeholders)
|
||||
|
||||
## Content Categories
|
||||
|
||||
Prebuilt categories use **keyword matching** to detect harmful content, bias, and inappropriate advice. Keywords are matched with word boundaries (single words) or as substrings (multi-word phrases), case-insensitive.
|
||||
|
||||
### Available Categories
|
||||
|
||||
| Category | Description |
|
||||
|----------|-------------|
|
||||
| **Harmful Content** | |
|
||||
| `harmful_self_harm` | Self-harm, suicide, eating disorders |
|
||||
| `harmful_violence` | Violence, criminal planning, attacks |
|
||||
| `harmful_illegal_weapons` | Illegal weapons, explosives, dangerous materials |
|
||||
| **Bias Detection** | |
|
||||
| `bias_gender` | Gender-based discrimination, stereotypes |
|
||||
| `bias_sexual_orientation` | LGBTQ+ discrimination, homophobia, transphobia |
|
||||
| `bias_racial` | Racial/ethnic discrimination, stereotypes |
|
||||
| `bias_religious` | Religious discrimination, stereotypes |
|
||||
| **Denied Advice** | |
|
||||
| `denied_financial_advice` | Personalized financial advice, investment recommendations |
|
||||
| `denied_medical_advice` | Medical advice, diagnosis, treatment recommendations |
|
||||
| `denied_legal_advice` | Legal advice, representation, legal strategy |
|
||||
|
||||
:::info Bias Detection Considerations
|
||||
|
||||
Bias detection is **complex and context-dependent**. Rule-based systems catch explicit discriminatory language but may generate false positives on legitimate discussions. Start with **high severity thresholds** and test thoroughly. For mission-critical bias detection, consider combining with AI-based guardrails (e.g., HiddenLayer, Lakera).
|
||||
|
||||
:::
|
||||
|
||||
### Configuration
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
guardrails:
|
||||
- guardrail_name: "content-filter"
|
||||
litellm_params:
|
||||
guardrail: litellm_content_filter
|
||||
mode: "pre_call"
|
||||
|
||||
categories:
|
||||
- category: "harmful_self_harm"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "medium" # Blocks medium+ severity
|
||||
|
||||
- category: "bias_gender"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "high" # Only explicit discrimination
|
||||
|
||||
- category: "denied_financial_advice"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "medium"
|
||||
```
|
||||
|
||||
**Severity Thresholds:**
|
||||
- `"high"` - Only blocks high severity items
|
||||
- `"medium"` - Blocks medium and high severity (default)
|
||||
- `"low"` - Blocks all severity levels
|
||||
|
||||
### Custom Category Files
|
||||
|
||||
Override default categories with custom keyword lists:
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
categories:
|
||||
- category: "harmful_self_harm"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "medium"
|
||||
category_file: "/path/to/custom.yaml"
|
||||
```
|
||||
|
||||
```yaml showLineNumbers title="custom.yaml"
|
||||
category_name: "harmful_self_harm"
|
||||
description: "Custom self-harm detection"
|
||||
default_action: "BLOCK"
|
||||
|
||||
keywords:
|
||||
- keyword: "suicide"
|
||||
severity: "high"
|
||||
- keyword: "harm myself"
|
||||
severity: "high"
|
||||
|
||||
exceptions:
|
||||
- "suicide prevention"
|
||||
- "mental health"
|
||||
```
|
||||
|
||||
## Use Cases
|
||||
|
||||
### 1. PII Protection
|
||||
### 1. Harmful Content Detection
|
||||
|
||||
Block or detect requests containing harmful, illegal, or dangerous content:
|
||||
|
||||
```yaml
|
||||
categories:
|
||||
- category: "harmful_self_harm"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "medium"
|
||||
- category: "harmful_violence"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "high"
|
||||
- category: "harmful_illegal_weapons"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "medium"
|
||||
```
|
||||
|
||||
### 2. Bias and Discrimination Detection
|
||||
|
||||
Detect and block biased, discriminatory, or hateful content across multiple dimensions:
|
||||
|
||||
```yaml
|
||||
categories:
|
||||
# Gender-based discrimination
|
||||
- category: "bias_gender"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "medium"
|
||||
|
||||
# LGBTQ+ discrimination
|
||||
- category: "bias_sexual_orientation"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "medium"
|
||||
|
||||
# Racial/ethnic discrimination
|
||||
- category: "bias_racial"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "high" # Only explicit to reduce false positives
|
||||
|
||||
# Religious discrimination
|
||||
- category: "bias_religious"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "medium"
|
||||
```
|
||||
|
||||
**Sensitivity Tuning:**
|
||||
|
||||
For bias detection, severity thresholds are critical to balance safety and legitimate discourse:
|
||||
|
||||
```yaml
|
||||
# Conservative (low false positives, may miss subtle bias)
|
||||
categories:
|
||||
- category: "bias_racial"
|
||||
severity_threshold: "high" # Only blocks explicit discriminatory language
|
||||
|
||||
# Balanced (recommended)
|
||||
categories:
|
||||
- category: "bias_gender"
|
||||
severity_threshold: "medium" # Blocks stereotypes and explicit discrimination
|
||||
|
||||
# Strict (high safety, may have more false positives)
|
||||
categories:
|
||||
- category: "bias_sexual_orientation"
|
||||
severity_threshold: "low" # Blocks all potentially problematic content
|
||||
```
|
||||
|
||||
|
||||
|
||||
### 3. PII Protection
|
||||
Block or mask personally identifiable information before sending to LLMs:
|
||||
|
||||
```yaml
|
||||
|
|
@ -409,10 +732,64 @@ For large lists of sensitive terms, use a file:
|
|||
blocked_words_file: "/path/to/sensitive_terms.yaml"
|
||||
```
|
||||
|
||||
### 4. Compliance
|
||||
### 4. Safe AI for Consumer Applications
|
||||
|
||||
Combining harmful content and bias detection for consumer-facing AI:
|
||||
|
||||
```yaml
|
||||
guardrails:
|
||||
- guardrail_name: "safe-consumer-ai"
|
||||
litellm_params:
|
||||
guardrail: litellm_content_filter
|
||||
mode: "pre_call"
|
||||
|
||||
categories:
|
||||
# Harmful content - strict
|
||||
- category: "harmful_self_harm"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "medium"
|
||||
|
||||
- category: "harmful_violence"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "medium"
|
||||
|
||||
# Bias detection - balanced
|
||||
- category: "bias_gender"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "high" # Avoid blocking legitimate gender discussions
|
||||
|
||||
- category: "bias_sexual_orientation"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "medium"
|
||||
|
||||
- category: "bias_racial"
|
||||
enabled: true
|
||||
action: "BLOCK"
|
||||
severity_threshold: "high" # Education and news may discuss race
|
||||
```
|
||||
|
||||
**Perfect for:**
|
||||
- Chatbots and virtual assistants
|
||||
- Educational AI tools
|
||||
- Customer service AI
|
||||
- Content generation platforms
|
||||
- Public-facing AI applications
|
||||
|
||||
### 5. Compliance
|
||||
Ensure regulatory compliance by filtering sensitive data types:
|
||||
|
||||
```yaml
|
||||
# Categories checked first (high priority)
|
||||
# Category keywords are matched first
|
||||
categories:
|
||||
- category: "harmful_self_harm"
|
||||
severity_threshold: "high"
|
||||
|
||||
# Then regex patterns
|
||||
patterns:
|
||||
- pattern_type: "prebuilt"
|
||||
pattern_name: "visa"
|
||||
|
|
@ -422,34 +799,4 @@ patterns:
|
|||
action: "BLOCK"
|
||||
```
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
### Pattern Not Matching
|
||||
|
||||
**Issue:** Regex pattern isn't detecting expected content
|
||||
|
||||
**Solution:** Test your regex pattern:
|
||||
```python
|
||||
import re
|
||||
pattern = r'\b[A-Z]{3}-\d{4}\b'
|
||||
test_text = "Employee ID: ABC-1234"
|
||||
print(re.search(pattern, test_text)) # Should match
|
||||
```
|
||||
|
||||
### Multiple Pattern Matches
|
||||
|
||||
**Issue:** Text contains multiple sensitive patterns
|
||||
|
||||
**Solution:** First matching pattern/keyword is processed. Order patterns by priority:
|
||||
```yaml
|
||||
patterns:
|
||||
# Most critical first
|
||||
- pattern_type: "prebuilt"
|
||||
pattern_name: "us_ssn"
|
||||
action: "BLOCK"
|
||||
# Less critical
|
||||
- pattern_type: "prebuilt"
|
||||
pattern_name: "email"
|
||||
action: "MASK"
|
||||
```
|
||||
|
||||
|
|
|
|||
|
|
@ -790,7 +790,7 @@ curl -X POST "http://localhost:4000/v1/chat/completions" \
|
|||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Generate python code that accesses my Github repo using this PAT: ghp_A1b2C3d4E5f6G7h8I9j0K1l2M3n4O5p6Q7r8"
|
||||
"content": "Generate python code that accesses my Github repo using this PAT: example-github-token-123"
|
||||
}
|
||||
],
|
||||
"max_tokens": 50
|
||||
|
|
@ -815,7 +815,7 @@ curl -X POST "http://localhost:4000/v1/chat/completions" \
|
|||
"type": "github_token",
|
||||
"start_idx": 66,
|
||||
"end_idx": 106,
|
||||
"evidence": "ghp_A1b2C3d4E5f6G7h8I9j0K1l2M3n4O5p6Q7r8",
|
||||
"evidence": "example-github-token-123",
|
||||
}
|
||||
]
|
||||
}
|
||||
|
|
|
|||
|
|
@ -69,6 +69,13 @@ guardrails:
|
|||
- `during_call` Run **during** LLM call, on **input** Same as `pre_call` but runs in parallel as LLM call. Response not returned until guardrail check completes
|
||||
- A list of the above values to run multiple modes, e.g. `mode: [pre_call, post_call]`
|
||||
|
||||
### Load Balancing Guardrails
|
||||
|
||||
Need to distribute guardrail requests across multiple accounts or regions? See [Guardrail Load Balancing](./guardrail_load_balancing.md) for details on:
|
||||
- Load balancing across multiple AWS Bedrock accounts (useful for rate limit management)
|
||||
- Weighted distribution across guardrail instances
|
||||
- Multi-region guardrail deployments
|
||||
|
||||
|
||||
## 2. Start LiteLLM Gateway
|
||||
|
||||
|
|
|
|||
|
|
@ -16,6 +16,7 @@ Log Proxy input, output, and exceptions using:
|
|||
- Custom Callbacks - Custom code and API endpoints
|
||||
- Langsmith
|
||||
- DataDog
|
||||
- Azure Sentinel
|
||||
- DynamoDB
|
||||
- etc.
|
||||
|
||||
|
|
@ -1574,6 +1575,10 @@ curl --location 'http://0.0.0.0:4000/chat/completions' \
|
|||
|
||||
👉 Go here for using [Datadog LLM Observability](../observability/datadog) with LiteLLM Proxy
|
||||
|
||||
## [Azure Sentinel](../observability/azure_sentinel)
|
||||
|
||||
👉 Go here for using [Azure Sentinel](../observability/azure_sentinel) with LiteLLM Proxy
|
||||
|
||||
|
||||
## Lunary
|
||||
#### Step1: Install dependencies and set your environment variables
|
||||
|
|
|
|||
|
|
@ -89,7 +89,7 @@ curl -X POST 'http://0.0.0.0:4000/team/update' \
|
|||
"id": "bd136c28-edd0-4cb6-b963-f35464cf6f5a",
|
||||
"updated_at": "2024-06-08 23:41:14.793",
|
||||
"changed_by": "krrish@berri.ai", # 👈 CHANGED BY
|
||||
"changed_by_api_key": "88dc28d0f030c55ed4ab77ed8faf098196cb1c05df778539800c9f1243fe6b4b",
|
||||
"changed_by_api_key": "example-api-key-123",
|
||||
"action": "updated",
|
||||
"table_name": "LiteLLM_TeamTable",
|
||||
"object_id": "8bf18b11-7f52-4717-8e1f-7c65f9d01e52",
|
||||
|
|
|
|||
|
|
@ -33,7 +33,7 @@ litellm_settings:
|
|||
|
||||
Set slack webhook url in your env
|
||||
```shell
|
||||
export SLACK_WEBHOOK_URL="https://hooks.slack.com/services/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"
|
||||
export SLACK_WEBHOOK_URL="example-slack-webhook-url"
|
||||
```
|
||||
|
||||
Turn off FASTAPI's default info logs
|
||||
|
|
|
|||
|
|
@ -400,7 +400,7 @@ from anthropic import Anthropic
|
|||
|
||||
client = Anthropic(
|
||||
base_url="http://localhost:4000", # proxy endpoint
|
||||
api_key="sk-s4xN1IiLTCytwtZFJaYQrA", # litellm proxy virtual key
|
||||
api_key="sk-test-proxy-key-123", # litellm proxy virtual key (example)
|
||||
)
|
||||
|
||||
message = client.messages.create(
|
||||
|
|
|
|||
|
|
@ -285,7 +285,7 @@ from anthropic import Anthropic
|
|||
|
||||
client = Anthropic(
|
||||
base_url="http://localhost:4000", # proxy endpoint
|
||||
api_key="sk-s4xN1IiLTCytwtZFJaYQrA", # litellm proxy virtual key
|
||||
api_key="sk-test-proxy-key-123", # litellm proxy virtual key (example)
|
||||
)
|
||||
|
||||
message = client.messages.create(
|
||||
|
|
|
|||
|
|
@ -4,7 +4,7 @@ import TabItem from '@theme/TabItem';
|
|||
# /responses
|
||||
|
||||
|
||||
LiteLLM provides a BETA endpoint in the spec of [OpenAI's `/responses` API](https://platform.openai.com/docs/api-reference/responses)
|
||||
LiteLLM provides an endpoint in the spec of [OpenAI's `/responses` API](https://platform.openai.com/docs/api-reference/responses)
|
||||
|
||||
Requests to /chat/completions may be bridged here automatically when the provider lacks support for that endpoint. The model’s default `mode` determines how bridging works.(see `model_prices_and_context_window`)
|
||||
|
||||
|
|
|
|||
|
|
@ -2,7 +2,7 @@
|
|||
|
||||
| Feature | Supported |
|
||||
|---------|-----------|
|
||||
| Supported Providers | `perplexity`, `tavily`, `parallel_ai`, `exa_ai`, `google_pse`, `dataforseo`, `firecrawl`, `searxng` |
|
||||
| Supported Providers | `perplexity`, `tavily`, `parallel_ai`, `exa_ai`, `google_pse`, `dataforseo`, `firecrawl`, `searxng`, `linkup` |
|
||||
| Cost Tracking | ✅ |
|
||||
| Logging | ✅ |
|
||||
| Load Balancing | ❌ |
|
||||
|
|
@ -205,7 +205,7 @@ See the [official Perplexity Search documentation](https://docs.perplexity.ai/ap
|
|||
| Parameter | Type | Required | Description |
|
||||
|-----------|------|----------|-------------|
|
||||
| `query` | string or array | Yes | Search query. Can be a single string or array of strings |
|
||||
| `search_provider` | string | Yes (SDK) | The search provider to use: `"perplexity"`, `"tavily"`, `"parallel_ai"`, `"exa_ai"`, `"google_pse"`, `"dataforseo"`, `"firecrawl"`, or `"searxng"` |
|
||||
| `search_provider` | string | Yes (SDK) | The search provider to use: `"perplexity"`, `"tavily"`, `"parallel_ai"`, `"exa_ai"`, `"google_pse"`, `"dataforseo"`, `"firecrawl"`, `"searxng"`, or `"linkup"` |
|
||||
| `search_tool_name` | string | Yes (Proxy) | Name of the search tool configured in `config.yaml` |
|
||||
| `max_results` | integer | No | Maximum number of results to return (1-20). Default: 10 |
|
||||
| `search_domain_filter` | array | No | List of domains to filter results (max 20 domains) |
|
||||
|
|
@ -269,6 +269,7 @@ The response follows Perplexity's search format with the following structure:
|
|||
| DataForSEO | `DATAFORSEO_LOGIN`, `DATAFORSEO_PASSWORD` | `dataforseo` |
|
||||
| Firecrawl | `FIRECRAWL_API_KEY` | `firecrawl` |
|
||||
| SearXNG | `SEARXNG_API_BASE` (required) | `searxng` |
|
||||
| Linkup | `LINKUP_API_KEY` | `linkup` |
|
||||
|
||||
See the individual provider documentation for detailed setup instructions and provider-specific parameters.
|
||||
|
||||
|
|
|
|||
152
docs/my-website/docs/search/linkup.md
Normal file
|
|
@ -0,0 +1,152 @@
|
|||
# Linkup Search
|
||||
|
||||
**Get API Key:** [https://linkup.so](https://linkup.so)
|
||||
|
||||
## LiteLLM Python SDK
|
||||
|
||||
```python showLineNumbers title="Linkup Search"
|
||||
import os
|
||||
from litellm import search
|
||||
|
||||
os.environ["LINKUP_API_KEY"] = "..."
|
||||
|
||||
response = search(
|
||||
query="latest AI developments",
|
||||
search_provider="linkup",
|
||||
max_results=5
|
||||
)
|
||||
```
|
||||
|
||||
## LiteLLM AI Gateway
|
||||
|
||||
### 1. Setup config.yaml
|
||||
|
||||
```yaml showLineNumbers title="config.yaml"
|
||||
model_list:
|
||||
- model_name: gpt-4
|
||||
litellm_params:
|
||||
model: gpt-4
|
||||
api_key: os.environ/OPENAI_API_KEY
|
||||
|
||||
search_tools:
|
||||
- search_tool_name: linkup-search
|
||||
litellm_params:
|
||||
search_provider: linkup
|
||||
api_key: os.environ/LINKUP_API_KEY
|
||||
```
|
||||
|
||||
### 2. Start the proxy
|
||||
|
||||
```bash
|
||||
litellm --config /path/to/config.yaml
|
||||
|
||||
# RUNNING on http://0.0.0.0:4000
|
||||
```
|
||||
|
||||
### 3. Test the search endpoint
|
||||
|
||||
```bash showLineNumbers title="Test Request"
|
||||
curl http://0.0.0.0:4000/v1/search/linkup-search \
|
||||
-H "Authorization: Bearer sk-1234" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"query": "latest AI developments",
|
||||
"max_results": 5
|
||||
}'
|
||||
```
|
||||
|
||||
## Provider-specific Parameters
|
||||
|
||||
```python showLineNumbers title="Linkup Search with Provider-specific Parameters"
|
||||
import os
|
||||
from litellm import search
|
||||
|
||||
os.environ["LINKUP_API_KEY"] = "..."
|
||||
|
||||
response = search(
|
||||
query="machine learning research",
|
||||
search_provider="linkup",
|
||||
max_results=10,
|
||||
# Linkup-specific parameters
|
||||
depth="deep", # "standard" (faster) or "deep" (more comprehensive)
|
||||
outputType="searchResults", # "searchResults", "sourcedAnswer", or "structured"
|
||||
includeSources=True, # Include sources in response
|
||||
includeImages=True, # Include images in results
|
||||
fromDate="2024-01-01", # Start date filter (YYYY-MM-DD)
|
||||
toDate="2024-12-31", # End date filter (YYYY-MM-DD)
|
||||
includeDomains=["arxiv.org", "nature.com"], # Domains to search (max 100)
|
||||
excludeDomains=["wikipedia.com"], # Domains to exclude
|
||||
includeInlineCitations=True, # Include inline citations in sourcedAnswer
|
||||
)
|
||||
```
|
||||
|
||||
## Features
|
||||
|
||||
Linkup provides powerful web search with context retrieval capabilities:
|
||||
|
||||
### Search Depth
|
||||
Control the precision and speed of your search:
|
||||
- `standard` - Returns results faster
|
||||
- `deep` - Takes longer but yields more comprehensive results
|
||||
|
||||
### Output Types
|
||||
Choose how results are formatted:
|
||||
- `searchResults` - Returns a list of search results with URLs and content
|
||||
- `sourcedAnswer` - Returns an AI-generated answer with sources
|
||||
- `structured` - Returns results in a custom JSON schema format
|
||||
|
||||
### Date Filtering
|
||||
Filter results by date range:
|
||||
```python
|
||||
response = search(
|
||||
query="AI developments",
|
||||
search_provider="linkup",
|
||||
fromDate="2024-06-01",
|
||||
toDate="2024-12-31"
|
||||
)
|
||||
```
|
||||
|
||||
### Domain Filtering
|
||||
Include or exclude specific domains:
|
||||
```python
|
||||
response = search(
|
||||
query="research papers",
|
||||
search_provider="linkup",
|
||||
includeDomains=["arxiv.org", "nature.com", "ieee.org"],
|
||||
excludeDomains=["wikipedia.com"]
|
||||
)
|
||||
```
|
||||
|
||||
### Structured Output
|
||||
Get results in a custom JSON schema format:
|
||||
```python
|
||||
response = search(
|
||||
query="Microsoft 2024 revenue",
|
||||
search_provider="linkup",
|
||||
outputType="structured",
|
||||
structuredOutputSchema='{"type": "object", "properties": {"revenue": {"type": "string"}, "year": {"type": "string"}}}'
|
||||
)
|
||||
```
|
||||
|
||||
## Response Format
|
||||
|
||||
Linkup returns results in the following format:
|
||||
|
||||
```json
|
||||
{
|
||||
"results": [
|
||||
{
|
||||
"type": "text",
|
||||
"name": "Microsoft 2024 Annual Report",
|
||||
"url": "https://www.microsoft.com/investor/reports/ar24/index.html",
|
||||
"content": "Highlights from fiscal year 2024..."
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
LiteLLM transforms this to the standard `SearchResponse` format:
|
||||
- `results[].name` → `SearchResult.title`
|
||||
- `results[].url` → `SearchResult.url`
|
||||
- `results[].content` → `SearchResult.snippet`
|
||||
|
||||
|
|
@ -197,3 +197,27 @@ When a Virtual Key is Created / Deleted on LiteLLM, LiteLLM will automatically c
|
|||
LiteLLM stores secret under the `prefix_for_stored_virtual_keys` path (default: `litellm/`)
|
||||
|
||||
<Image img={require('../../img/hcorp_virtual_key.png')} />
|
||||
|
||||
### Team-specific overrides
|
||||
|
||||
When running the LiteLLM proxy you can override the Vault location per team. Use the [Team-Level Secret Manager Settings](./overview.md#team-level-secret-manager-settings) flow in the dashboard and configure the panel shown below:
|
||||
|
||||
<Image img={require('../../img/secret_manager_hashicorp_vault_settings.png')} />
|
||||
|
||||
Use the following structure for the JSON payload:
|
||||
|
||||
```json
|
||||
{
|
||||
"namespace": "teams/team-a",
|
||||
"mount": "kv-prod",
|
||||
"path_prefix": "virtual-keys",
|
||||
"data": "password"
|
||||
}
|
||||
```
|
||||
|
||||
- `namespace` – overrides the `X-Vault-Namespace` header.
|
||||
- `mount` – which KV engine mount to use (defaults to `secret`).
|
||||
- `path_prefix` – additional path segments between the mount and the secret name.
|
||||
- `data` – the field name inside the KV payload (defaults to `key`).
|
||||
|
||||
Whenever LiteLLM stores or deletes virtual keys for that team, these overrides are applied so you can keep each team’s credentials in its own namespace, mount, or field layout without changing the global Vault configuration.
|
||||
|
|
|
|||
|
|
@ -1,3 +1,5 @@
|
|||
import Image from '@theme/IdealImage';
|
||||
|
||||
# Secret Managers Overview
|
||||
|
||||
:::info
|
||||
|
|
@ -45,3 +47,30 @@ general_settings:
|
|||
primary_secret_name: "litellm_secrets" # OPTIONAL. Read multiple keys from one JSON secret on AWS Secret Manager
|
||||
```
|
||||
|
||||
## Team-Level Secret Manager Settings
|
||||
|
||||
Team-level secret manager settings let every team bring their own key-management configuration. These settings are used when creating virtual keys tied to the team.
|
||||
|
||||
Follow these steps to configure it:
|
||||
|
||||
1. **Create a team**
|
||||
Open the Teams page and click `Create Team` to launch the modal.
|
||||
|
||||
<Image img={require('../../img/secret_manager_settings_create_team.png')} />
|
||||
|
||||
2. **Expand Additional Settings**
|
||||
Use the `Additional Settings` toggle to reveal the advanced configuration panel.
|
||||
|
||||
<Image img={require('../../img/secret_manager_settings_additional_settings.png')} />
|
||||
|
||||
3. **Configure the Secret Manager**
|
||||
In the `Secret Manager Settings` panel, paste the provider-specific JSON. Refer to each provider page (AWS, Azure, Google, Hashicorp, etc.) for the supported keys/values. JSON is required today, but we plan to add a more UI-friendly editor.
|
||||
|
||||
<Image img={require('../../img/secret_manager_settings.png')} />
|
||||
|
||||
4. **Create the team**
|
||||
Review the inputs and click `Create Team` to save.
|
||||
|
||||
<Image img={require('../../img/secret_manager_settings_create_button.png')} />
|
||||
|
||||
Once saved, LiteLLM will use this configuration.
|
||||
|
|
|
|||
|
|
@ -14,7 +14,7 @@ import TabItem from '@theme/TabItem';
|
|||
| Fallbacks | ✅ | Works between supported models |
|
||||
| Loadbalancing | ✅ | Works between supported models |
|
||||
| Guardrails | ✅ | Applies to input text (non-streaming only) |
|
||||
| Supported Providers | OpenAI, Azure OpenAI, Vertex AI | |
|
||||
| Supported Providers | OpenAI, Azure OpenAI, Vertex AI, AWS Polly, ElevenLabs | |
|
||||
|
||||
## **LiteLLM Python SDK Usage**
|
||||
### Quick Start
|
||||
|
|
@ -101,6 +101,7 @@ litellm --config /path/to/config.yaml
|
|||
| OpenAI | [Usage](#quick-start) |
|
||||
| Azure OpenAI| [Usage](../docs/providers/azure#azure-text-to-speech-tts) |
|
||||
| Azure AI Speech Service (AVA)| [Usage](../docs/providers/azure_ai_speech) |
|
||||
| AWS Polly | [Usage](#aws-polly-text-to-speech) |
|
||||
| Vertex AI | [Usage](../docs/providers/vertex#text-to-speech-apis) |
|
||||
| Gemini | [Usage](#gemini-text-to-speech) |
|
||||
| ElevenLabs | [Usage](../docs/providers/elevenlabs#text-to-speech-tts) |
|
||||
|
|
@ -246,6 +247,12 @@ curl http://0.0.0.0:4000/v1/audio/speech \
|
|||
--output vertex_speech.mp3
|
||||
```
|
||||
|
||||
### AWS Polly Text-to-Speech
|
||||
|
||||
AWS Polly provides neural and standard text-to-speech engines with support for multiple voices and languages.
|
||||
|
||||
See the [AWS Polly provider documentation](../docs/providers/aws_polly) for detailed usage examples.
|
||||
|
||||
## ✨ Enterprise LiteLLM Proxy - Set Max Request File Size
|
||||
|
||||
Use this when you want to limit the file size for requests sent to `audio/transcriptions`
|
||||
|
|
|
|||
BIN
docs/my-website/img/secret_manager_hashicorp_vault_settings.png
Normal file

|
After Width: | Height: | Size: 107 KiB |
BIN
docs/my-website/img/secret_manager_settings.png
Normal file

|
After Width: | Height: | Size: 680 KiB |

|
After Width: | Height: | Size: 683 KiB |
BIN
docs/my-website/img/secret_manager_settings_create_button.png
Normal file

|
After Width: | Height: | Size: 691 KiB |
BIN
docs/my-website/img/secret_manager_settings_create_team.png
Normal file

|
After Width: | Height: | Size: 524 KiB |
BIN
docs/my-website/img/sentinel.png
Normal file

|
After Width: | Height: | Size: 918 KiB |
BIN
docs/my-website/img/ui_cloudzero.png
Normal file

|
After Width: | Height: | Size: 58 KiB |
37
docs/my-website/package-lock.json
generated
|
|
@ -180,6 +180,7 @@
|
|||
"resolved": "https://registry.npmjs.org/@algolia/client-search/-/client-search-5.44.0.tgz",
|
||||
"integrity": "sha512-/FRKUM1G4xn3vV8+9xH1WJ9XknU8rkBGlefruq9jDhYUAvYozKimhrmC2pRqw/RyHhPivmgZCRuC8jHP8piz4Q==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"@algolia/client-common": "5.44.0",
|
||||
"@algolia/requester-browser-xhr": "5.44.0",
|
||||
|
|
@ -327,6 +328,7 @@
|
|||
"resolved": "https://registry.npmjs.org/@babel/core/-/core-7.28.5.tgz",
|
||||
"integrity": "sha512-e7jT4DxYvIDLk1ZHmU/m/mB19rex9sv0c2ftBtjSBv+kVM/902eh0fINUzD7UwLLNR+jU585GxUJ8/EBfAM5fw==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"@babel/code-frame": "^7.27.1",
|
||||
"@babel/generator": "^7.28.5",
|
||||
|
|
@ -2161,6 +2163,7 @@
|
|||
}
|
||||
],
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"engines": {
|
||||
"node": ">=18"
|
||||
},
|
||||
|
|
@ -2183,6 +2186,7 @@
|
|||
}
|
||||
],
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"engines": {
|
||||
"node": ">=18"
|
||||
}
|
||||
|
|
@ -2292,6 +2296,7 @@
|
|||
"resolved": "https://registry.npmjs.org/postcss-selector-parser/-/postcss-selector-parser-7.1.0.tgz",
|
||||
"integrity": "sha512-8sLjZwK0R+JlxlYcTuVnyT2v+htpdrjDOKuMcOVdYjt52Lh8hWRYpxBPoKx/Zg+bcjc3wx6fmQevMmUztS/ccA==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"cssesc": "^3.0.0",
|
||||
"util-deprecate": "^1.0.2"
|
||||
|
|
@ -2713,6 +2718,7 @@
|
|||
"resolved": "https://registry.npmjs.org/postcss-selector-parser/-/postcss-selector-parser-7.1.0.tgz",
|
||||
"integrity": "sha512-8sLjZwK0R+JlxlYcTuVnyT2v+htpdrjDOKuMcOVdYjt52Lh8hWRYpxBPoKx/Zg+bcjc3wx6fmQevMmUztS/ccA==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"cssesc": "^3.0.0",
|
||||
"util-deprecate": "^1.0.2"
|
||||
|
|
@ -3589,6 +3595,7 @@
|
|||
"resolved": "https://registry.npmjs.org/@docusaurus/plugin-content-docs/-/plugin-content-docs-3.8.1.tgz",
|
||||
"integrity": "sha512-oByRkSZzeGNQByCMaX+kif5Nl2vmtj2IHQI2fWjCfCootsdKZDPFLonhIp5s3IGJO7PLUfe0POyw0Xh/RrGXJA==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"@docusaurus/core": "3.8.1",
|
||||
"@docusaurus/logger": "3.8.1",
|
||||
|
|
@ -4627,6 +4634,7 @@
|
|||
"resolved": "https://registry.npmjs.org/@mdx-js/react/-/react-3.1.1.tgz",
|
||||
"integrity": "sha512-f++rKLQgUVYDAtECQ6fn/is15GkEH9+nZPM3MS0RcxVqoTfawHvDlSCH7JbMhAM6uJ32v3eXLvLmLvjGu7PTQw==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"@types/mdx": "^2.0.0"
|
||||
},
|
||||
|
|
@ -7183,6 +7191,7 @@
|
|||
"resolved": "https://registry.npmjs.org/@svgr/core/-/core-8.1.0.tgz",
|
||||
"integrity": "sha512-8QqtOQT5ACVlmsvKOJNEaWmRPmcojMOzCz4Hs2BGG/toAp/K38LcsMRyLp349glq5AzJbCEeimEoxaX6v/fLrA==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"@babel/core": "^7.21.3",
|
||||
"@svgr/babel-preset": "8.1.0",
|
||||
|
|
@ -7840,6 +7849,7 @@
|
|||
"resolved": "https://registry.npmjs.org/@types/react/-/react-19.2.6.tgz",
|
||||
"integrity": "sha512-p/jUvulfgU7oKtj6Xpk8cA2Y1xKTtICGpJYeJXz2YVO2UcvjQgeRMLDGfDeqeRW2Ta+0QNFwcc8X3GH8SxZz6w==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"csstype": "^3.2.2"
|
||||
}
|
||||
|
|
@ -8264,6 +8274,7 @@
|
|||
"resolved": "https://registry.npmjs.org/acorn/-/acorn-8.15.0.tgz",
|
||||
"integrity": "sha512-NZyJarBfL7nWwIq+FDL6Zp/yHEhePMNnnJ0y3qfieCrmNvYct8uvtiV41UvlSe6apAfk0fY1FbWx+NwfmpvtTg==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"bin": {
|
||||
"acorn": "bin/acorn"
|
||||
},
|
||||
|
|
@ -8343,6 +8354,7 @@
|
|||
"resolved": "https://registry.npmjs.org/ajv/-/ajv-8.17.1.tgz",
|
||||
"integrity": "sha512-B/gBuNg5SiMTrPkC+A2+cW0RszwxYmn6VYxB/inlBStS5nx6xHIt/ehKRhIMhqusl7a8LjQoZnjCs5vhwxOQ1g==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"fast-deep-equal": "^3.1.3",
|
||||
"fast-uri": "^3.0.1",
|
||||
|
|
@ -8388,6 +8400,7 @@
|
|||
"resolved": "https://registry.npmjs.org/algoliasearch/-/algoliasearch-5.44.0.tgz",
|
||||
"integrity": "sha512-f8IpsbdQjzTjr/4mJ/jv5UplrtyMnnciGax6/B0OnLCs2/GJTK13O4Y7Ff1AvJVAaztanH+m5nzPoUq6EAy+aA==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"@algolia/abtesting": "1.10.0",
|
||||
"@algolia/client-abtesting": "5.44.0",
|
||||
|
|
@ -8421,9 +8434,9 @@
|
|||
}
|
||||
},
|
||||
"node_modules/altcha-lib": {
|
||||
"version": "1.3.0",
|
||||
"resolved": "https://registry.npmjs.org/altcha-lib/-/altcha-lib-1.3.0.tgz",
|
||||
"integrity": "sha512-PpFg/JPuR+Jiud7Vs54XSDqDxvylcp+0oDa/i1ARxBA/iKDqLeNlO8PorQbfuDTMVLYRypAa/2VDK3nbBTAu5A==",
|
||||
"version": "1.4.1",
|
||||
"resolved": "https://registry.npmjs.org/altcha-lib/-/altcha-lib-1.4.1.tgz",
|
||||
"integrity": "sha512-MAXP9tkQOA2SE9Gwoe3LAcZbcDpp3XzYc5GDVej/y3eMNaFG/eVnRY1/7SGFW0RPsViEjPf+hi5eANjuZrH1xA==",
|
||||
"license": "MIT"
|
||||
},
|
||||
"node_modules/ansi-align": {
|
||||
|
|
@ -9029,6 +9042,7 @@
|
|||
}
|
||||
],
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"baseline-browser-mapping": "^2.8.25",
|
||||
"caniuse-lite": "^1.0.30001754",
|
||||
|
|
@ -9364,6 +9378,7 @@
|
|||
"resolved": "https://registry.npmjs.org/chevrotain/-/chevrotain-11.0.3.tgz",
|
||||
"integrity": "sha512-ci2iJH6LeIkvP9eJW6gpueU8cnZhv85ELY8w8WiFtNjMHA5ad6pQLaJo9mEly/9qUyCpvqX8/POVUTf18/HFdw==",
|
||||
"license": "Apache-2.0",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"@chevrotain/cst-dts-gen": "11.0.3",
|
||||
"@chevrotain/gast": "11.0.3",
|
||||
|
|
@ -10127,6 +10142,7 @@
|
|||
"resolved": "https://registry.npmjs.org/postcss-selector-parser/-/postcss-selector-parser-7.1.0.tgz",
|
||||
"integrity": "sha512-8sLjZwK0R+JlxlYcTuVnyT2v+htpdrjDOKuMcOVdYjt52Lh8hWRYpxBPoKx/Zg+bcjc3wx6fmQevMmUztS/ccA==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"cssesc": "^3.0.0",
|
||||
"util-deprecate": "^1.0.2"
|
||||
|
|
@ -10446,6 +10462,7 @@
|
|||
"resolved": "https://registry.npmjs.org/cytoscape/-/cytoscape-3.33.1.tgz",
|
||||
"integrity": "sha512-iJc4TwyANnOGR1OmWhsS9ayRS3s+XQ185FmuHObThD+5AeJCakAAbWv8KimMTt08xCCLNgneQwFp+JRJOr9qGQ==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"engines": {
|
||||
"node": ">=0.10"
|
||||
}
|
||||
|
|
@ -10855,6 +10872,7 @@
|
|||
"resolved": "https://registry.npmjs.org/d3-selection/-/d3-selection-3.0.0.tgz",
|
||||
"integrity": "sha512-fmTRWbNMmsmWq6xJV8D19U/gw/bwrHfNXxrIN+HfZgnzqTHp9jOmKMhsTUjXOJnZOdZY9Q28y4yebKzqDKlxlQ==",
|
||||
"license": "ISC",
|
||||
"peer": true,
|
||||
"engines": {
|
||||
"node": ">=12"
|
||||
}
|
||||
|
|
@ -12111,6 +12129,7 @@
|
|||
"resolved": "https://registry.npmjs.org/ajv/-/ajv-6.12.6.tgz",
|
||||
"integrity": "sha512-j3fVLgvTo527anyYyJOGTYJbG+vnnQYvE0m5mmkc1TK+nxAppkCLMIL0aZ4dblVCNoGShhm+kzE4ZUykBoMg4g==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"fast-deep-equal": "^3.1.1",
|
||||
"fast-json-stable-stringify": "^2.0.0",
|
||||
|
|
@ -16990,6 +17009,7 @@
|
|||
"resolved": "https://registry.npmjs.org/ajv/-/ajv-6.12.6.tgz",
|
||||
"integrity": "sha512-j3fVLgvTo527anyYyJOGTYJbG+vnnQYvE0m5mmkc1TK+nxAppkCLMIL0aZ4dblVCNoGShhm+kzE4ZUykBoMg4g==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"fast-deep-equal": "^3.1.1",
|
||||
"fast-json-stable-stringify": "^2.0.0",
|
||||
|
|
@ -17610,6 +17630,7 @@
|
|||
}
|
||||
],
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"nanoid": "^3.3.11",
|
||||
"picocolors": "^1.1.1",
|
||||
|
|
@ -18513,6 +18534,7 @@
|
|||
"resolved": "https://registry.npmjs.org/postcss-selector-parser/-/postcss-selector-parser-7.1.0.tgz",
|
||||
"integrity": "sha512-8sLjZwK0R+JlxlYcTuVnyT2v+htpdrjDOKuMcOVdYjt52Lh8hWRYpxBPoKx/Zg+bcjc3wx6fmQevMmUztS/ccA==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"cssesc": "^3.0.0",
|
||||
"util-deprecate": "^1.0.2"
|
||||
|
|
@ -19404,6 +19426,7 @@
|
|||
"resolved": "https://registry.npmjs.org/react/-/react-19.2.0.tgz",
|
||||
"integrity": "sha512-tmbWg6W31tQLeB5cdIBOicJDJRR2KzXsV7uSK9iNfLWQ5bIZfxuPEHp7M8wiHyHnn0DD1i7w3Zmin0FtkrwoCQ==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"engines": {
|
||||
"node": ">=0.10.0"
|
||||
}
|
||||
|
|
@ -19413,6 +19436,7 @@
|
|||
"resolved": "https://registry.npmjs.org/react-dom/-/react-dom-19.2.0.tgz",
|
||||
"integrity": "sha512-UlbRu4cAiGaIewkPyiRGJk0imDN2T3JjieT6spoL2UeSf5od4n5LB/mQ4ejmxhCFT1tYe8IvaFulzynWovsEFQ==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"scheduler": "^0.27.0"
|
||||
},
|
||||
|
|
@ -19496,6 +19520,7 @@
|
|||
"resolved": "https://registry.npmjs.org/@docusaurus/react-loadable/-/react-loadable-6.0.0.tgz",
|
||||
"integrity": "sha512-YMMxTUQV/QFSnbgrP3tjDzLHRg7vsbMn8e9HAa8o/1iXoiomo48b7sk/kkmWEuWNDPJVlKSJRB6Y2fHqdJk+SQ==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"@types/react": "*"
|
||||
},
|
||||
|
|
@ -19597,6 +19622,7 @@
|
|||
"resolved": "https://registry.npmjs.org/react-router/-/react-router-5.3.4.tgz",
|
||||
"integrity": "sha512-Ys9K+ppnJah3QuaRiLxk+jDWOR1MekYQrlytiXxC1RyfbdsZkS5pvKAzCCr031xHixZwpnsYNT5xysdFHQaYsA==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"@babel/runtime": "^7.12.13",
|
||||
"history": "^4.9.0",
|
||||
|
|
@ -21615,7 +21641,8 @@
|
|||
"version": "2.8.1",
|
||||
"resolved": "https://registry.npmjs.org/tslib/-/tslib-2.8.1.tgz",
|
||||
"integrity": "sha512-oJFu94HQb+KVduSUQL7wnpmqnfmLsOA/nAh6b6EH0wCEoK0/mPeXU6c3wKDV83MkOuHPRHtSXKKU99IBazS/2w==",
|
||||
"license": "0BSD"
|
||||
"license": "0BSD",
|
||||
"peer": true
|
||||
},
|
||||
"node_modules/tunnel-agent": {
|
||||
"version": "0.6.0",
|
||||
|
|
@ -22002,6 +22029,7 @@
|
|||
"resolved": "https://registry.npmjs.org/ajv/-/ajv-6.12.6.tgz",
|
||||
"integrity": "sha512-j3fVLgvTo527anyYyJOGTYJbG+vnnQYvE0m5mmkc1TK+nxAppkCLMIL0aZ4dblVCNoGShhm+kzE4ZUykBoMg4g==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"fast-deep-equal": "^3.1.1",
|
||||
"fast-json-stable-stringify": "^2.0.0",
|
||||
|
|
@ -22353,6 +22381,7 @@
|
|||
"resolved": "https://registry.npmjs.org/webpack/-/webpack-5.103.0.tgz",
|
||||
"integrity": "sha512-HU1JOuV1OavsZ+mfigY0j8d1TgQgbZ6M+J75zDkpEAwYeXjWSqrGJtgnPblJjd/mAyTNQ7ygw0MiKOn6etz8yw==",
|
||||
"license": "MIT",
|
||||
"peer": true,
|
||||
"dependencies": {
|
||||
"@types/eslint-scope": "^3.7.7",
|
||||
"@types/estree": "^1.0.8",
|
||||
|
|
|
|||
385
docs/my-website/release_notes/v1.80.11-stable/index.md
Normal file
|
|
@ -0,0 +1,385 @@
|
|||
---
|
||||
title: "[Preview] v1.80.11 - Google Interactions API"
|
||||
slug: "v1-80-11"
|
||||
date: 2025-12-20T10:00:00
|
||||
authors:
|
||||
- name: Krrish Dholakia
|
||||
title: CEO, LiteLLM
|
||||
url: https://www.linkedin.com/in/krish-d/
|
||||
image_url: https://pbs.twimg.com/profile_images/1298587542745358340/DZv3Oj-h_400x400.jpg
|
||||
- name: Ishaan Jaff
|
||||
title: CTO, LiteLLM
|
||||
url: https://www.linkedin.com/in/reffajnaahsi/
|
||||
image_url: https://pbs.twimg.com/profile_images/1613813310264340481/lz54oEiB_400x400.jpg
|
||||
hide_table_of_contents: false
|
||||
---
|
||||
|
||||
import Image from '@theme/IdealImage';
|
||||
import Tabs from '@theme/Tabs';
|
||||
import TabItem from '@theme/TabItem';
|
||||
|
||||
## Deploy this version
|
||||
|
||||
<Tabs>
|
||||
<TabItem value="docker" label="Docker">
|
||||
|
||||
``` showLineNumbers title="docker run litellm"
|
||||
docker run \
|
||||
-e STORE_MODEL_IN_DB=True \
|
||||
-p 4000:4000 \
|
||||
docker.litellm.ai/berriai/litellm:v1.80.11.rc.1
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
|
||||
<TabItem value="pip" label="Pip">
|
||||
|
||||
``` showLineNumbers title="pip install litellm"
|
||||
pip install litellm==1.80.11
|
||||
```
|
||||
|
||||
</TabItem>
|
||||
</Tabs>
|
||||
|
||||
---
|
||||
|
||||
## Key Highlights
|
||||
|
||||
- **Gemini 3 Flash Preview** - [Day 0 support for Google's Gemini 3 Flash Preview with reasoning capabilities](../../docs/providers/gemini)
|
||||
- **Stability AI Image Generation** - [New provider for Stability AI image generation and editing](../../docs/providers/stability)
|
||||
- **LiteLLM Content Filter** - [Built-in guardrails for harmful content, bias, and PII detection with image support](../../docs/proxy/guardrails/litellm_content_filter)
|
||||
- **New Provider: Venice.ai** - Support for Venice.ai API via providers.json
|
||||
- **Unified Skills API** - [Skills API works across Anthropic, Vertex, Azure, and Bedrock](../../docs/skills)
|
||||
- **Azure Sentinel Logging** - [New logging integration for Azure Sentinel](../../docs/observability/azure_sentinel)
|
||||
- **Guardrails Load Balancing** - [Load balance between multiple guardrail providers](../../docs/proxy/guardrails)
|
||||
- **Email Budget Alerts** - [Send email notifications when budgets are reached](../../docs/proxy/email)
|
||||
- **Cloudzero Integration on UI** - Setup your Cloudzero Integration Directly on the UI
|
||||
|
||||
---
|
||||
|
||||
### Cloudzero Integration on UI
|
||||
|
||||
<Image
|
||||
img={require('../../img/ui_cloudzero.png')}
|
||||
style={{width: '100%', display: 'block', margin: '2rem auto'}}
|
||||
/>
|
||||
|
||||
Users can now configure their Cloudzero Integration directly on the UI.
|
||||
|
||||
---
|
||||
### Performance: 50% Reduction in Memory Usage and Import Latency for the LiteLLM SDK
|
||||
|
||||
We've completely restructured `litellm.__init__.py` to defer heavy imports until they're actually needed, implementing lazy loading for **109 components**.
|
||||
|
||||
This refactoring includes **41 provider config classes**, **40 utility functions**, cache implementations (Redis, DualCache, InMemoryCache), HTTP handlers, logging, types, and other heavy dependencies. Heavy libraries like tiktoken and boto3 are now loaded on-demand rather than eagerly at import time.
|
||||
|
||||
This makes LiteLLM especially beneficial for serverless functions, Lambda deployments, and containerized environments where cold start times and memory footprint matter.
|
||||
|
||||
---
|
||||
|
||||
## New Providers and Endpoints
|
||||
|
||||
### New Providers (5 new providers)
|
||||
|
||||
| Provider | Supported LiteLLM Endpoints | Description |
|
||||
| -------- | ------------------- | ----------- |
|
||||
| [Stability AI](../../docs/providers/stability) | `/images/generations`, `/images/edits` | Stable Diffusion 3, SD3.5, image editing and generation |
|
||||
| Venice.ai | `/chat/completions`, `/messages`, `/responses` | Venice.ai API integration via providers.json |
|
||||
| [Pydantic AI Agents](../../docs/providers/pydantic_ai_agent) | `/a2a` | Pydantic AI agents for A2A protocol workflows |
|
||||
| [VertexAI Agent Engine](../../docs/providers/vertex_ai_agent_engine) | `/a2a` | Google Vertex AI Agent Engine for agentic workflows |
|
||||
| [LinkUp Search](../../docs/search/linkup) | `/search` | LinkUp web search API integration |
|
||||
|
||||
### New LLM API Endpoints (2 new endpoints)
|
||||
|
||||
| Endpoint | Method | Description | Documentation |
|
||||
| -------- | ------ | ----------- | ------------- |
|
||||
| `/interactions` | POST | Google Interactions API for conversational AI | [Docs](../../docs/interactions) |
|
||||
| `/search` | POST | RAG Search API with rerankers | [Docs](../../docs/search/index) |
|
||||
|
||||
---
|
||||
|
||||
## New Models / Updated Models
|
||||
|
||||
#### New Model Support (55+ new models)
|
||||
|
||||
| Provider | Model | Context Window | Input ($/1M tokens) | Output ($/1M tokens) | Features |
|
||||
| -------- | ----- | -------------- | ------------------- | -------------------- | -------- |
|
||||
| Gemini | `gemini/gemini-3-flash-preview` | 1M | $0.50 | $3.00 | Reasoning, vision, audio, video, PDF |
|
||||
| Vertex AI | `vertex_ai/gemini-3-flash-preview` | 1M | $0.50 | $3.00 | Reasoning, vision, audio, video, PDF |
|
||||
| Azure AI | `azure_ai/deepseek-v3.2` | 164K | $0.58 | $1.68 | Reasoning, function calling, caching |
|
||||
| Azure AI | `azure_ai/cohere-rerank-v4.0-pro` | 32K | $0.0025/query | - | Rerank |
|
||||
| Azure AI | `azure_ai/cohere-rerank-v4.0-fast` | 32K | $0.002/query | - | Rerank |
|
||||
| OpenRouter | `openrouter/openai/gpt-5.2` | 400K | $1.75 | $14.00 | Reasoning, vision, caching |
|
||||
| OpenRouter | `openrouter/openai/gpt-5.2-pro` | 400K | $21.00 | $168.00 | Reasoning, vision |
|
||||
| OpenRouter | `openrouter/mistralai/devstral-2512` | 262K | $0.15 | $0.60 | Function calling |
|
||||
| OpenRouter | `openrouter/mistralai/ministral-3b-2512` | 131K | $0.10 | $0.10 | Function calling, vision |
|
||||
| OpenRouter | `openrouter/mistralai/ministral-8b-2512` | 262K | $0.15 | $0.15 | Function calling, vision |
|
||||
| OpenRouter | `openrouter/mistralai/ministral-14b-2512` | 262K | $0.20 | $0.20 | Function calling, vision |
|
||||
| OpenRouter | `openrouter/mistralai/mistral-large-2512` | 262K | $0.50 | $1.50 | Function calling, vision |
|
||||
| OpenAI | `gpt-4o-transcribe-diarize` | 16K | $6.00/audio | - | Audio transcription with diarization |
|
||||
| OpenAI | `gpt-image-1.5-2025-12-16` | - | Various | Various | Image generation |
|
||||
| Stability | `stability/sd3-large` | - | - | $0.065/image | Image generation |
|
||||
| Stability | `stability/sd3.5-large` | - | - | $0.065/image | Image generation |
|
||||
| Stability | `stability/stable-image-ultra` | - | - | $0.08/image | Image generation |
|
||||
| Stability | `stability/inpaint` | - | - | $0.005/image | Image editing |
|
||||
| Stability | `stability/outpaint` | - | - | $0.004/image | Image editing |
|
||||
| Bedrock | `stability.stable-conservative-upscale-v1:0` | - | - | $0.40/image | Image upscaling |
|
||||
| Bedrock | `stability.stable-creative-upscale-v1:0` | - | - | $0.60/image | Image upscaling |
|
||||
| Vertex AI | `vertex_ai/deepseek-ai/deepseek-ocr-maas` | - | $0.30 | $1.20 | OCR |
|
||||
| LinkUp | `linkup/search` | - | $5.87/1K queries | - | Web search |
|
||||
| LinkUp | `linkup/search-deep` | - | $58.67/1K queries | - | Deep web search |
|
||||
| GitHub Copilot | 20+ models | Various | - | - | Chat completions |
|
||||
|
||||
#### Features
|
||||
|
||||
- **[Gemini](../../docs/providers/gemini)**
|
||||
- Add Gemini 3 Flash Preview day 0 support with reasoning - [PR #18135](https://github.com/BerriAI/litellm/pull/18135)
|
||||
- Support extra_headers in batch embeddings - [PR #18004](https://github.com/BerriAI/litellm/pull/18004)
|
||||
- Propagate token usage when generating images - [PR #17987](https://github.com/BerriAI/litellm/pull/17987)
|
||||
- Use JSON instead of form-data for image edit requests - [PR #18012](https://github.com/BerriAI/litellm/pull/18012)
|
||||
- Fix web search requests count - [PR #17921](https://github.com/BerriAI/litellm/pull/17921)
|
||||
- **[Anthropic](../../docs/providers/anthropic)**
|
||||
- Use dynamic max_tokens based on model - [PR #17900](https://github.com/BerriAI/litellm/pull/17900)
|
||||
- Fix claude-3-7-sonnet max_tokens to 64K default - [PR #17979](https://github.com/BerriAI/litellm/pull/17979)
|
||||
- Add OpenAI-compatible API with modify_params=True - [PR #17106](https://github.com/BerriAI/litellm/pull/17106)
|
||||
- **[Vertex AI](../../docs/providers/vertex)**
|
||||
- Add Gemini 3 Flash Preview support - [PR #18164](https://github.com/BerriAI/litellm/pull/18164)
|
||||
- Add reasoning support for gemini-3-flash-preview - [PR #18175](https://github.com/BerriAI/litellm/pull/18175)
|
||||
- Fix image edit credential source - [PR #18121](https://github.com/BerriAI/litellm/pull/18121)
|
||||
- Pass credentials to PredictionServiceClient for custom endpoints - [PR #17757](https://github.com/BerriAI/litellm/pull/17757)
|
||||
- Fix multimodal embeddings for text + base64 image combinations - [PR #18172](https://github.com/BerriAI/litellm/pull/18172)
|
||||
- Add OCR support for DeepSeek model - [PR #17971](https://github.com/BerriAI/litellm/pull/17971)
|
||||
- **[Azure AI](../../docs/providers/azure_ai)**
|
||||
- Add Azure Cohere 4 reranking models - [PR #17961](https://github.com/BerriAI/litellm/pull/17961)
|
||||
- Add Azure DeepSeek V3.2 versions - [PR #18019](https://github.com/BerriAI/litellm/pull/18019)
|
||||
- Return AzureAnthropicConfig for Claude models in get_provider_chat_config - [PR #18086](https://github.com/BerriAI/litellm/pull/18086)
|
||||
- **[Fireworks AI](../../docs/providers/fireworks_ai)**
|
||||
- Add reasoning param support for Fireworks AI models - [PR #17967](https://github.com/BerriAI/litellm/pull/17967)
|
||||
- **[Bedrock](../../docs/providers/bedrock)**
|
||||
- Add Qwen 2 and Qwen 3 to get_bedrock_model_id - [PR #18100](https://github.com/BerriAI/litellm/pull/18100)
|
||||
- Remove ttl field when routing to bedrock - [PR #18049](https://github.com/BerriAI/litellm/pull/18049)
|
||||
- Add Bedrock Stability image edit models - [PR #18254](https://github.com/BerriAI/litellm/pull/18254)
|
||||
- **[Perplexity](../../docs/providers/perplexity)**
|
||||
- Use API-provided cost instead of manual calculation - [PR #17887](https://github.com/BerriAI/litellm/pull/17887)
|
||||
- **[OpenAI](../../docs/providers/openai)**
|
||||
- Add diarize model for audio transcription - [PR #18117](https://github.com/BerriAI/litellm/pull/18117)
|
||||
- Add gpt-image-1.5-2025-12-16 in model cost map - [PR #18107](https://github.com/BerriAI/litellm/pull/18107)
|
||||
- Fix cost calculation of gpt-image-1 model - [PR #17966](https://github.com/BerriAI/litellm/pull/17966)
|
||||
- **[GitHub Copilot](../../docs/providers/github_copilot)**
|
||||
- Add github_copilot model info - [PR #17858](https://github.com/BerriAI/litellm/pull/17858)
|
||||
- **[Custom LLM](../../docs/providers/custom_llm_server)**
|
||||
- Add image_edit and aimage_edit support - [PR #17999](https://github.com/BerriAI/litellm/pull/17999)
|
||||
|
||||
### Bug Fixes
|
||||
|
||||
- **[Gemini](../../docs/providers/gemini)**
|
||||
- Fix pricing for Gemini 3 Flash on Vertex AI - [PR #18202](https://github.com/BerriAI/litellm/pull/18202)
|
||||
- Add output_cost_per_image_token for gemini-2.5-flash-image models - [PR #18156](https://github.com/BerriAI/litellm/pull/18156)
|
||||
- Fix properties should be non-empty for OBJECT type - [PR #18237](https://github.com/BerriAI/litellm/pull/18237)
|
||||
- **[Qwen](../../docs/providers/fireworks_ai)**
|
||||
- Add qwen3-embedding-8b input per token price - [PR #18018](https://github.com/BerriAI/litellm/pull/18018)
|
||||
- **General**
|
||||
- Fix image URL handling - [PR #18139](https://github.com/BerriAI/litellm/pull/18139)
|
||||
- Support Signed URLs with Query Parameters in Image Processing - [PR #17976](https://github.com/BerriAI/litellm/pull/17976)
|
||||
- Add none to encoding_format instead of omitting it - [PR #18042](https://github.com/BerriAI/litellm/pull/18042)
|
||||
|
||||
---
|
||||
|
||||
## LLM API Endpoints
|
||||
|
||||
#### Features
|
||||
|
||||
- **[Responses API](../../docs/response_api)**
|
||||
- Add provider specific tools support - [PR #17980](https://github.com/BerriAI/litellm/pull/17980)
|
||||
- Add custom headers support - [PR #18036](https://github.com/BerriAI/litellm/pull/18036)
|
||||
- Fix tool calls transformation in completion bridge - [PR #18226](https://github.com/BerriAI/litellm/pull/18226)
|
||||
- Use list format with input_text for tool results - [PR #18257](https://github.com/BerriAI/litellm/pull/18257)
|
||||
- Add cost tracking in background mode - [PR #18236](https://github.com/BerriAI/litellm/pull/18236)
|
||||
- Fix Claude code responses API bridge errors - [PR #18194](https://github.com/BerriAI/litellm/pull/18194)
|
||||
- **[Chat Completions API](../../docs/completion/input)**
|
||||
- Add support for agent skills - [PR #18031](https://github.com/BerriAI/litellm/pull/18031)
|
||||
- **[Skills API](../../docs/skills)**
|
||||
- Unified Skills API works across Anthropic, Vertex, Azure, Bedrock - [PR #18232](https://github.com/BerriAI/litellm/pull/18232)
|
||||
- **[Search API](../../docs/search/index)**
|
||||
- Add new RAG Search API with rerankers - [PR #18217](https://github.com/BerriAI/litellm/pull/18217)
|
||||
- **[Interactions API](../../docs/interactions)**
|
||||
- Add Google Interactions API on SDK and AI Gateway - [PR #18079](https://github.com/BerriAI/litellm/pull/18079), [PR #18081](https://github.com/BerriAI/litellm/pull/18081)
|
||||
- **[Image Edit API](../../docs/image_edits)**
|
||||
- Add drop_params support and fix Vertex AI config - [PR #18077](https://github.com/BerriAI/litellm/pull/18077)
|
||||
- **General**
|
||||
- Skip adding beta headers for Vertex AI as it is not supported - [PR #18037](https://github.com/BerriAI/litellm/pull/18037)
|
||||
- Fix managed files endpoint - [PR #18046](https://github.com/BerriAI/litellm/pull/18046)
|
||||
- Allow base_model for non-Azure providers in proxy - [PR #18038](https://github.com/BerriAI/litellm/pull/18038)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- **General**
|
||||
- Fix basemodel import in guardrail translation - [PR #17977](https://github.com/BerriAI/litellm/pull/17977)
|
||||
- Fix No module named 'fastapi' error - [PR #18239](https://github.com/BerriAI/litellm/pull/18239)
|
||||
|
||||
---
|
||||
|
||||
## Management Endpoints / UI
|
||||
|
||||
#### Features
|
||||
|
||||
- **Virtual Keys**
|
||||
- Add master key rotation for credentials table - [PR #17952](https://github.com/BerriAI/litellm/pull/17952)
|
||||
- Fix tag management to preserve encrypted fields in litellm_params - [PR #17484](https://github.com/BerriAI/litellm/pull/17484)
|
||||
- Fix key delete and regenerate permissions - [PR #18214](https://github.com/BerriAI/litellm/pull/18214)
|
||||
- **Models + Endpoints**
|
||||
- Add Models Conditional Rendering in UI - [PR #18071](https://github.com/BerriAI/litellm/pull/18071)
|
||||
- Add Health Check Model for Wildcard Model in UI - [PR #18269](https://github.com/BerriAI/litellm/pull/18269)
|
||||
- Auto Resolve Vector Store Embedding Model Config - [PR #18167](https://github.com/BerriAI/litellm/pull/18167)
|
||||
- **Vector Stores**
|
||||
- Add Milvus Vector Store UI support - [PR #18030](https://github.com/BerriAI/litellm/pull/18030)
|
||||
- Persist Vector Store Settings in Team Update - [PR #18274](https://github.com/BerriAI/litellm/pull/18274)
|
||||
- **Logs & Spend**
|
||||
- Add LiteLLM Overhead to Logs - [PR #18033](https://github.com/BerriAI/litellm/pull/18033)
|
||||
- Show LiteLLM Overhead in Logs UI - [PR #18034](https://github.com/BerriAI/litellm/pull/18034)
|
||||
- Resolve Team ID to Team Alias in Usage Page - [PR #18275](https://github.com/BerriAI/litellm/pull/18275)
|
||||
- Fix Usage Page Top Key View Button Visibility - [PR #18203](https://github.com/BerriAI/litellm/pull/18203)
|
||||
- **SSO & Health**
|
||||
- Add SSO Readiness Health Check - [PR #18078](https://github.com/BerriAI/litellm/pull/18078)
|
||||
- Fix /health/test_connection to resolve env variables like /chat/completions - [PR #17752](https://github.com/BerriAI/litellm/pull/17752)
|
||||
- **CloudZero**
|
||||
- Add CloudZero Cost Tracking UI - [PR #18163](https://github.com/BerriAI/litellm/pull/18163)
|
||||
- Add Delete CloudZero Settings Route and UI - [PR #18168](https://github.com/BerriAI/litellm/pull/18168), [PR #18170](https://github.com/BerriAI/litellm/pull/18170)
|
||||
- **General**
|
||||
- Update UI path handling for non-root Docker - [PR #17989](https://github.com/BerriAI/litellm/pull/17989)
|
||||
|
||||
#### Bugs
|
||||
|
||||
- **UI Fixes**
|
||||
- Fix Login Page Failed To Parse JSON Error - [PR #18159](https://github.com/BerriAI/litellm/pull/18159)
|
||||
- Fix new user route user_id collision handling - [PR #17559](https://github.com/BerriAI/litellm/pull/17559)
|
||||
- Fix Callback Environment Variables Casing - [PR #17912](https://github.com/BerriAI/litellm/pull/17912)
|
||||
|
||||
---
|
||||
|
||||
## AI Integrations
|
||||
|
||||
### Logging
|
||||
|
||||
- **[Azure Sentinel](../../docs/observability/azure_sentinel)**
|
||||
- Add new Azure Sentinel Logger integration - [PR #18146](https://github.com/BerriAI/litellm/pull/18146)
|
||||
- **[Prometheus](../../docs/proxy/logging#prometheus)**
|
||||
- Add extraction of top level metadata for custom labels - [PR #18087](https://github.com/BerriAI/litellm/pull/18087)
|
||||
- **[Langfuse](../../docs/proxy/logging#langfuse)**
|
||||
- Fix not working log_failure_event - [PR #18234](https://github.com/BerriAI/litellm/pull/18234)
|
||||
- **[Arize Phoenix](../../docs/observability/phoenix_integration)**
|
||||
- Fix nested spans - [PR #18102](https://github.com/BerriAI/litellm/pull/18102)
|
||||
- **General**
|
||||
- Change extra_headers to additional_headers - [PR #17950](https://github.com/BerriAI/litellm/pull/17950)
|
||||
|
||||
### Guardrails
|
||||
|
||||
- **[LiteLLM Content Filter](../../docs/proxy/guardrails/litellm_content_filter)**
|
||||
- Add built-in guardrails for harmful content, bias, etc. - [PR #18029](https://github.com/BerriAI/litellm/pull/18029)
|
||||
- Add support for running content filters on images - [PR #18044](https://github.com/BerriAI/litellm/pull/18044)
|
||||
- Add support for Brazil PII field - [PR #18076](https://github.com/BerriAI/litellm/pull/18076)
|
||||
- Add configurable guardrail options for content filtering - [PR #18007](https://github.com/BerriAI/litellm/pull/18007)
|
||||
- **[Guardrails API](../../docs/adding_provider/generic_guardrail_api)**
|
||||
- Support LLM tool call response checks on `/chat/completions`, `/v1/responses`, `/v1/messages` - [PR #17619](https://github.com/BerriAI/litellm/pull/17619)
|
||||
- Add guardrails load balancing - [PR #18181](https://github.com/BerriAI/litellm/pull/18181)
|
||||
- Fix guardrails for passthrough endpoint - [PR #18109](https://github.com/BerriAI/litellm/pull/18109)
|
||||
- Add headers to metadata for guardrails on pass-through endpoints - [PR #17992](https://github.com/BerriAI/litellm/pull/17992)
|
||||
- Various fixes for guardrail on OpenRouter models - [PR #18085](https://github.com/BerriAI/litellm/pull/18085)
|
||||
- **[Lakera](../../docs/proxy/guardrails/lakera_ai)**
|
||||
- Add monitor mode for Lakera - [PR #18084](https://github.com/BerriAI/litellm/pull/18084)
|
||||
- **[Pillar Security](../../docs/proxy/guardrails/pillar_security)**
|
||||
- Add masking support and MCP call support - [PR #17959](https://github.com/BerriAI/litellm/pull/17959)
|
||||
- **[Bedrock Guardrails](../../docs/proxy/guardrails/bedrock)**
|
||||
- Add support for Bedrock image guardrails - [PR #18115](https://github.com/BerriAI/litellm/pull/18115)
|
||||
- Guardrails block action takes precedence over masking - [PR #17968](https://github.com/BerriAI/litellm/pull/17968)
|
||||
|
||||
### Secret Managers
|
||||
|
||||
- **[HashiCorp Vault](../../docs/secret_managers/hashicorp_vault)**
|
||||
- Add documentation for configurable Vault mount - [PR #18082](https://github.com/BerriAI/litellm/pull/18082)
|
||||
- Add per-team Vault configuration - [PR #18150](https://github.com/BerriAI/litellm/pull/18150)
|
||||
- **UI**
|
||||
- Add secret manager settings controls to team management UI - [PR #18149](https://github.com/BerriAI/litellm/pull/18149)
|
||||
|
||||
---
|
||||
|
||||
## Spend Tracking, Budgets and Rate Limiting
|
||||
|
||||
- **Email Budget Alerts** - Send email notifications when budgets are reached - [PR #17995](https://github.com/BerriAI/litellm/pull/17995)
|
||||
|
||||
---
|
||||
|
||||
## MCP Gateway
|
||||
|
||||
- **Auth Header Propagation** - Add MCP auth header propagation - [PR #17963](https://github.com/BerriAI/litellm/pull/17963)
|
||||
- **Fix deepcopy error** - Fix MCP tool call deepcopy error when processing requests - [PR #18010](https://github.com/BerriAI/litellm/pull/18010)
|
||||
- **Fix list tool** - Fix MCP list_tools not working without database connection - [PR #18161](https://github.com/BerriAI/litellm/pull/18161)
|
||||
|
||||
---
|
||||
|
||||
## Agent Gateway (A2A)
|
||||
|
||||
- **New Provider: Agent Gateway** - Add pydantic ai agents support - [PR #18013](https://github.com/BerriAI/litellm/pull/18013)
|
||||
- **VertexAI Agent Engine** - Add Vertex AI Agent Engine provider - [PR #18014](https://github.com/BerriAI/litellm/pull/18014)
|
||||
- **Fix model extraction** - Fix get_model_from_request() to extract model ID from Vertex AI passthrough URLs - [PR #18097](https://github.com/BerriAI/litellm/pull/18097)
|
||||
|
||||
---
|
||||
|
||||
## Performance / Loadbalancing / Reliability improvements
|
||||
|
||||
- **Lazy Imports** - Use per-attribute lazy imports and extract shared constants - [PR #17994](https://github.com/BerriAI/litellm/pull/17994)
|
||||
- **Lazy Load HTTP Handlers** - Lazy load http handlers - [PR #17997](https://github.com/BerriAI/litellm/pull/17997)
|
||||
- **Lazy Load Caches** - Lazy load caches - [PR #18001](https://github.com/BerriAI/litellm/pull/18001)
|
||||
- **Lazy Load Types** - Lazy load bedrock types, .types.utils, GuardrailItem - [PR #18053](https://github.com/BerriAI/litellm/pull/18053), [PR #18054](https://github.com/BerriAI/litellm/pull/18054), [PR #18072](https://github.com/BerriAI/litellm/pull/18072)
|
||||
- **Lazy Load Configs** - Lazy load 41 configuration classes - [PR #18267](https://github.com/BerriAI/litellm/pull/18267)
|
||||
- **Lazy Load Client Decorators** - Lazy load heavy client decorator imports - [PR #18064](https://github.com/BerriAI/litellm/pull/18064)
|
||||
- **Prisma Build Time** - Download Prisma binaries at build time instead of runtime for security restricted environments - [PR #17695](https://github.com/BerriAI/litellm/pull/17695)
|
||||
- **Docker Alpine** - Add libsndfile to Alpine image for ARM64 audio processing - [PR #18092](https://github.com/BerriAI/litellm/pull/18092)
|
||||
- **Security** - Prevent LiteLLM API key leakage on /health endpoint failures - [PR #18133](https://github.com/BerriAI/litellm/pull/18133)
|
||||
|
||||
---
|
||||
|
||||
## Documentation Updates
|
||||
|
||||
- **SAP Docs** - Update SAP documentation - [PR #17974](https://github.com/BerriAI/litellm/pull/17974)
|
||||
- **Pydantic AI Agents** - Add docs on using pydantic ai agents with LiteLLM A2A gateway - [PR #18026](https://github.com/BerriAI/litellm/pull/18026)
|
||||
- **Vertex AI Agent Engine** - Add Vertex AI Agent Engine documentation - [PR #18027](https://github.com/BerriAI/litellm/pull/18027)
|
||||
- **Router Order** - Add router order parameter documentation - [PR #18045](https://github.com/BerriAI/litellm/pull/18045)
|
||||
- **Secret Manager Settings** - Improve secret manager settings documentation - [PR #18235](https://github.com/BerriAI/litellm/pull/18235)
|
||||
- **Gemini 3 Flash** - Add version requirement in Gemini 3 Flash blog - [PR #18227](https://github.com/BerriAI/litellm/pull/18227)
|
||||
- **README** - Expand Responses API section and update endpoints - [PR #17354](https://github.com/BerriAI/litellm/pull/17354)
|
||||
- **Amazon Nova** - Add Amazon Nova to sidebar and supported models - [PR #18220](https://github.com/BerriAI/litellm/pull/18220)
|
||||
- **Benchmarks** - Add infrastructure recommendations to benchmarks documentation - [PR #18264](https://github.com/BerriAI/litellm/pull/18264)
|
||||
- **Broken Links** - Fix broken link corrections - [PR #18104](https://github.com/BerriAI/litellm/pull/18104)
|
||||
- **README Fixes** - Various README improvements - [PR #18206](https://github.com/BerriAI/litellm/pull/18206)
|
||||
|
||||
---
|
||||
|
||||
## Infrastructure / CI/CD
|
||||
|
||||
- **PR Templates** - Add LiteLLM team PR template and CI/CD rules - [PR #17983](https://github.com/BerriAI/litellm/pull/17983), [PR #17985](https://github.com/BerriAI/litellm/pull/17985)
|
||||
- **Issue Labeling** - Improve issue labeling with component dropdown and more provider keywords - [PR #17957](https://github.com/BerriAI/litellm/pull/17957)
|
||||
- **PR Template Cleanup** - Remove redundant fields from PR template - [PR #17956](https://github.com/BerriAI/litellm/pull/17956)
|
||||
- **Dependencies** - Bump altcha-lib from 1.3.0 to 1.4.1 - [PR #18017](https://github.com/BerriAI/litellm/pull/18017)
|
||||
|
||||
---
|
||||
|
||||
## New Contributors
|
||||
|
||||
* @dongbin-lunark made their first contribution in [PR #17757](https://github.com/BerriAI/litellm/pull/17757)
|
||||
* @qdrddr made their first contribution in [PR #18004](https://github.com/BerriAI/litellm/pull/18004)
|
||||
* @donicrosby made their first contribution in [PR #17962](https://github.com/BerriAI/litellm/pull/17962)
|
||||
* @NicolaivdSmagt made their first contribution in [PR #17992](https://github.com/BerriAI/litellm/pull/17992)
|
||||
* @Reapor-Yurnero made their first contribution in [PR #18085](https://github.com/BerriAI/litellm/pull/18085)
|
||||
* @jk-f5 made their first contribution in [PR #18086](https://github.com/BerriAI/litellm/pull/18086)
|
||||
* @castrapel made their first contribution in [PR #18077](https://github.com/BerriAI/litellm/pull/18077)
|
||||
* @dtikhonov made their first contribution in [PR #17484](https://github.com/BerriAI/litellm/pull/17484)
|
||||
* @opleonnn made their first contribution in [PR #18175](https://github.com/BerriAI/litellm/pull/18175)
|
||||
* @eurogig made their first contribution in [PR #18084](https://github.com/BerriAI/litellm/pull/18084)
|
||||
|
||||
---
|
||||
|
||||
## Full Changelog
|
||||
|
||||
**[View complete changelog on GitHub](https://github.com/BerriAI/litellm/compare/v1.80.10-nightly...v1.80.11)**
|
||||
|
||||
|
|
@ -42,6 +42,7 @@ const sidebars = {
|
|||
label: "Guardrails",
|
||||
items: [
|
||||
"proxy/guardrails/quick_start",
|
||||
"proxy/guardrails/guardrail_load_balancing",
|
||||
{
|
||||
type: "category",
|
||||
"label": "Contributing to Guardrails",
|
||||
|
|
@ -52,6 +53,7 @@ const sidebars = {
|
|||
]
|
||||
},
|
||||
"proxy/guardrails/test_playground",
|
||||
"proxy/guardrails/litellm_content_filter",
|
||||
...[
|
||||
"proxy/guardrails/aim_security",
|
||||
"proxy/guardrails/onyx_security",
|
||||
|
|
@ -63,7 +65,6 @@ const sidebars = {
|
|||
"proxy/guardrails/grayswan",
|
||||
"proxy/guardrails/hiddenlayer",
|
||||
"proxy/guardrails/lasso_security",
|
||||
"proxy/guardrails/litellm_content_filter",
|
||||
"proxy/guardrails/guardrails_ai",
|
||||
"proxy/guardrails/lakera_ai",
|
||||
"proxy/guardrails/model_armor",
|
||||
|
|
@ -288,7 +289,7 @@ const sidebars = {
|
|||
label: "All Endpoints (Swagger)",
|
||||
href: "https://litellm-api.up.railway.app/",
|
||||
},
|
||||
"proxy/enterprise",
|
||||
"proxy/enterprise",
|
||||
{
|
||||
type: "category",
|
||||
label: "Authentication",
|
||||
|
|
@ -469,10 +470,10 @@ const sidebars = {
|
|||
"proxy/managed_finetuning",
|
||||
]
|
||||
},
|
||||
"generateContent",
|
||||
"apply_guardrail",
|
||||
"bedrock_invoke",
|
||||
"interactions",
|
||||
"generateContent",
|
||||
"apply_guardrail",
|
||||
"bedrock_invoke",
|
||||
"interactions",
|
||||
{
|
||||
type: "category",
|
||||
label: "/images",
|
||||
|
|
@ -544,6 +545,7 @@ const sidebars = {
|
|||
"search/dataforseo",
|
||||
"search/firecrawl",
|
||||
"search/searxng",
|
||||
"search/linkup",
|
||||
]
|
||||
},
|
||||
"skills",
|
||||
|
|
@ -662,6 +664,7 @@ const sidebars = {
|
|||
"providers/bedrock_agents",
|
||||
"providers/bedrock_writer",
|
||||
"providers/bedrock_batches",
|
||||
"providers/aws_polly",
|
||||
"providers/bedrock_vector_store",
|
||||
]
|
||||
},
|
||||
|
|
@ -669,6 +672,7 @@ const sidebars = {
|
|||
"providers/ai21",
|
||||
"providers/aiml",
|
||||
"providers/aleph_alpha",
|
||||
"providers/amazon_nova",
|
||||
"providers/anyscale",
|
||||
"providers/baseten",
|
||||
"providers/bytez",
|
||||
|
|
@ -780,6 +784,7 @@ const sidebars = {
|
|||
]
|
||||
},
|
||||
"providers/xai",
|
||||
"providers/xiaomi_mimo",
|
||||
"providers/xinference",
|
||||
"providers/zai",
|
||||
],
|
||||
|
|
|
|||
BIN
enterprise/dist/litellm_enterprise-0.1.26-py3-none-any.whl
vendored
Normal file
BIN
enterprise/dist/litellm_enterprise-0.1.26.tar.gz
vendored
Normal file
BIN
enterprise/dist/litellm_enterprise-0.1.27-py3-none-any.whl
vendored
Normal file
BIN
enterprise/dist/litellm_enterprise-0.1.27.tar.gz
vendored
Normal file
|
|
@ -5,7 +5,7 @@ Base class for sending emails to user after creating keys or invite links
|
|||
|
||||
import json
|
||||
import os
|
||||
from typing import List, Optional
|
||||
from typing import List, Literal, Optional
|
||||
|
||||
from litellm_enterprise.types.enterprise_callbacks.send_emails import (
|
||||
EmailEvent,
|
||||
|
|
@ -15,6 +15,7 @@ from litellm_enterprise.types.enterprise_callbacks.send_emails import (
|
|||
)
|
||||
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
from litellm.caching.caching import DualCache
|
||||
from litellm.integrations.custom_logger import CustomLogger
|
||||
from litellm.integrations.email_templates.email_footer import EMAIL_FOOTER
|
||||
from litellm.integrations.email_templates.key_created_email import (
|
||||
|
|
@ -26,9 +27,17 @@ from litellm.integrations.email_templates.key_rotated_email import (
|
|||
from litellm.integrations.email_templates.user_invitation_email import (
|
||||
USER_INVITATION_EMAIL_TEMPLATE,
|
||||
)
|
||||
from litellm.proxy._types import InvitationNew, UserAPIKeyAuth, WebhookEvent
|
||||
from litellm.integrations.email_templates.templates import (
|
||||
MAX_BUDGET_ALERT_EMAIL_TEMPLATE,
|
||||
SOFT_BUDGET_ALERT_EMAIL_TEMPLATE,
|
||||
)
|
||||
from litellm.proxy._types import CallInfo, InvitationNew, UserAPIKeyAuth, WebhookEvent
|
||||
from litellm.secret_managers.main import get_secret_bool
|
||||
from litellm.types.integrations.slack_alerting import LITELLM_LOGO_URL
|
||||
from litellm.constants import (
|
||||
EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE,
|
||||
EMAIL_BUDGET_ALERT_TTL,
|
||||
)
|
||||
|
||||
|
||||
class BaseEmailLogger(CustomLogger):
|
||||
|
|
@ -40,6 +49,21 @@ class BaseEmailLogger(CustomLogger):
|
|||
EmailEvent.virtual_key_rotated: "LiteLLM: {event_message}",
|
||||
}
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
internal_usage_cache: Optional[DualCache] = None,
|
||||
**kwargs,
|
||||
):
|
||||
"""
|
||||
Initialize BaseEmailLogger
|
||||
|
||||
Args:
|
||||
internal_usage_cache: DualCache instance for preventing duplicate alerts
|
||||
**kwargs: Additional arguments passed to CustomLogger
|
||||
"""
|
||||
super().__init__(**kwargs)
|
||||
self.internal_usage_cache = internal_usage_cache or DualCache()
|
||||
|
||||
async def send_user_invitation_email(self, event: WebhookEvent):
|
||||
"""
|
||||
Send email to user after inviting them to the team
|
||||
|
|
@ -154,6 +178,218 @@ class BaseEmailLogger(CustomLogger):
|
|||
)
|
||||
pass
|
||||
|
||||
async def send_soft_budget_alert_email(self, event: WebhookEvent):
|
||||
"""
|
||||
Send email to user when soft budget is crossed
|
||||
"""
|
||||
email_params = await self._get_email_params(
|
||||
email_event=EmailEvent.soft_budget_crossed, # Reuse existing event type for subject template
|
||||
user_id=event.user_id,
|
||||
user_email=event.user_email,
|
||||
event_message=event.event_message,
|
||||
)
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
f"send_soft_budget_alert_email_event: {json.dumps(event.model_dump(exclude_none=True), indent=4, default=str)}"
|
||||
)
|
||||
|
||||
# Format budget values
|
||||
soft_budget_str = f"${event.soft_budget}" if event.soft_budget is not None else "N/A"
|
||||
spend_str = f"${event.spend}" if event.spend is not None else "$0.00"
|
||||
max_budget_info = ""
|
||||
if event.max_budget is not None:
|
||||
max_budget_info = f"<b>Maximum Budget:</b> ${event.max_budget} <br />"
|
||||
|
||||
email_html_content = SOFT_BUDGET_ALERT_EMAIL_TEMPLATE.format(
|
||||
email_logo_url=email_params.logo_url,
|
||||
recipient_email=email_params.recipient_email,
|
||||
soft_budget=soft_budget_str,
|
||||
spend=spend_str,
|
||||
max_budget_info=max_budget_info,
|
||||
base_url=email_params.base_url,
|
||||
email_support_contact=email_params.support_contact,
|
||||
)
|
||||
await self.send_email(
|
||||
from_email=self.DEFAULT_LITELLM_EMAIL,
|
||||
to_email=[email_params.recipient_email],
|
||||
subject=email_params.subject,
|
||||
html_body=email_html_content,
|
||||
)
|
||||
pass
|
||||
|
||||
async def send_max_budget_alert_email(self, event: WebhookEvent):
|
||||
"""
|
||||
Send email to user when max budget alert threshold is reached
|
||||
"""
|
||||
email_params = await self._get_email_params(
|
||||
email_event=EmailEvent.max_budget_alert,
|
||||
user_id=event.user_id,
|
||||
user_email=event.user_email,
|
||||
event_message=event.event_message,
|
||||
)
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
f"send_max_budget_alert_email_event: {json.dumps(event.model_dump(exclude_none=True), indent=4, default=str)}"
|
||||
)
|
||||
|
||||
# Format budget values
|
||||
spend_str = f"${event.spend}" if event.spend is not None else "$0.00"
|
||||
max_budget_str = f"${event.max_budget}" if event.max_budget is not None else "N/A"
|
||||
|
||||
# Calculate percentage and alert threshold
|
||||
percentage = int(EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE * 100)
|
||||
alert_threshold_str = f"${event.max_budget * EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE:.2f}" if event.max_budget is not None else "N/A"
|
||||
|
||||
email_html_content = MAX_BUDGET_ALERT_EMAIL_TEMPLATE.format(
|
||||
email_logo_url=email_params.logo_url,
|
||||
recipient_email=email_params.recipient_email,
|
||||
percentage=percentage,
|
||||
spend=spend_str,
|
||||
max_budget=max_budget_str,
|
||||
alert_threshold=alert_threshold_str,
|
||||
base_url=email_params.base_url,
|
||||
email_support_contact=email_params.support_contact,
|
||||
)
|
||||
await self.send_email(
|
||||
from_email=self.DEFAULT_LITELLM_EMAIL,
|
||||
to_email=[email_params.recipient_email],
|
||||
subject=email_params.subject,
|
||||
html_body=email_html_content,
|
||||
)
|
||||
pass
|
||||
|
||||
async def budget_alerts(
|
||||
self,
|
||||
type: Literal[
|
||||
"token_budget",
|
||||
"soft_budget",
|
||||
"max_budget_alert",
|
||||
"user_budget",
|
||||
"team_budget",
|
||||
"organization_budget",
|
||||
"proxy_budget",
|
||||
"projected_limit_exceeded",
|
||||
],
|
||||
user_info: CallInfo,
|
||||
):
|
||||
"""
|
||||
Send a budget alert via email
|
||||
|
||||
Args:
|
||||
type: The type of budget alert to send
|
||||
user_info: The user info to send the alert for
|
||||
"""
|
||||
## PREVENTITIVE ALERTING ##
|
||||
# - Alert once within 24hr period
|
||||
# - Cache this information
|
||||
# - Don't re-alert, if alert already sent
|
||||
_cache: DualCache = self.internal_usage_cache
|
||||
|
||||
# percent of max_budget left to spend
|
||||
if user_info.max_budget is None and user_info.soft_budget is None:
|
||||
return
|
||||
|
||||
# For soft_budget alerts, check if we've already sent an alert
|
||||
if type == "soft_budget":
|
||||
if user_info.soft_budget is not None and user_info.spend >= user_info.soft_budget:
|
||||
# Generate cache key based on event type and identifier
|
||||
_id = user_info.token or user_info.user_id or "default_id"
|
||||
_cache_key = f"email_budget_alerts:soft_budget_crossed:{_id}"
|
||||
|
||||
# Check if we've already sent this alert
|
||||
result = await _cache.async_get_cache(key=_cache_key)
|
||||
if result is None:
|
||||
# Create WebhookEvent for soft budget alert
|
||||
event_message = f"Soft Budget Crossed - Total Soft Budget: ${user_info.soft_budget}"
|
||||
webhook_event = WebhookEvent(
|
||||
event="soft_budget_crossed",
|
||||
event_message=event_message,
|
||||
spend=user_info.spend,
|
||||
max_budget=user_info.max_budget,
|
||||
soft_budget=user_info.soft_budget,
|
||||
token=user_info.token,
|
||||
customer_id=user_info.customer_id,
|
||||
user_id=user_info.user_id,
|
||||
team_id=user_info.team_id,
|
||||
team_alias=user_info.team_alias,
|
||||
organization_id=user_info.organization_id,
|
||||
user_email=user_info.user_email,
|
||||
key_alias=user_info.key_alias,
|
||||
projected_exceeded_date=user_info.projected_exceeded_date,
|
||||
projected_spend=user_info.projected_spend,
|
||||
event_group=user_info.event_group,
|
||||
)
|
||||
|
||||
try:
|
||||
await self.send_soft_budget_alert_email(webhook_event)
|
||||
|
||||
# Cache the alert to prevent duplicate sends
|
||||
await _cache.async_set_cache(
|
||||
key=_cache_key,
|
||||
value="SENT",
|
||||
ttl=EMAIL_BUDGET_ALERT_TTL,
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.error(
|
||||
f"Error sending soft budget alert email: {e}",
|
||||
exc_info=True,
|
||||
)
|
||||
return
|
||||
|
||||
# For max_budget_alert, check if we've already sent an alert
|
||||
if type == "max_budget_alert":
|
||||
if user_info.max_budget is not None and user_info.spend is not None:
|
||||
alert_threshold = user_info.max_budget * EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE
|
||||
|
||||
# Only alert if we've crossed the threshold but haven't exceeded max_budget yet
|
||||
if user_info.spend >= alert_threshold and user_info.spend < user_info.max_budget:
|
||||
# Generate cache key based on event type and identifier
|
||||
_id = user_info.token or user_info.user_id or "default_id"
|
||||
_cache_key = f"email_budget_alerts:max_budget_alert:{_id}"
|
||||
|
||||
# Check if we've already sent this alert
|
||||
result = await _cache.async_get_cache(key=_cache_key)
|
||||
if result is None:
|
||||
# Calculate percentage
|
||||
percentage = int(EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE * 100)
|
||||
|
||||
# Create WebhookEvent for max budget alert
|
||||
event_message = f"Max Budget Alert - {percentage}% of Maximum Budget Reached"
|
||||
webhook_event = WebhookEvent(
|
||||
event="max_budget_alert",
|
||||
event_message=event_message,
|
||||
spend=user_info.spend,
|
||||
max_budget=user_info.max_budget,
|
||||
soft_budget=user_info.soft_budget,
|
||||
token=user_info.token,
|
||||
customer_id=user_info.customer_id,
|
||||
user_id=user_info.user_id,
|
||||
team_id=user_info.team_id,
|
||||
team_alias=user_info.team_alias,
|
||||
organization_id=user_info.organization_id,
|
||||
user_email=user_info.user_email,
|
||||
key_alias=user_info.key_alias,
|
||||
projected_exceeded_date=user_info.projected_exceeded_date,
|
||||
projected_spend=user_info.projected_spend,
|
||||
event_group=user_info.event_group,
|
||||
)
|
||||
|
||||
try:
|
||||
await self.send_max_budget_alert_email(webhook_event)
|
||||
|
||||
# Cache the alert to prevent duplicate sends
|
||||
await _cache.async_set_cache(
|
||||
key=_cache_key,
|
||||
value="SENT",
|
||||
ttl=EMAIL_BUDGET_ALERT_TTL,
|
||||
)
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.error(
|
||||
f"Error sending max budget alert email: {e}",
|
||||
exc_info=True,
|
||||
)
|
||||
return
|
||||
|
||||
async def _get_email_params(
|
||||
self,
|
||||
email_event: EmailEvent,
|
||||
|
|
|
|||
|
|
@ -19,7 +19,8 @@ RESEND_API_ENDPOINT = "https://api.resend.com/emails"
|
|||
|
||||
|
||||
class ResendEmailLogger(BaseEmailLogger):
|
||||
def __init__(self):
|
||||
def __init__(self, internal_usage_cache=None, **kwargs):
|
||||
super().__init__(internal_usage_cache=internal_usage_cache, **kwargs)
|
||||
self.async_httpx_client = get_async_httpx_client(
|
||||
llm_provider=httpxSpecialProvider.LoggingCallback
|
||||
)
|
||||
|
|
|
|||
|
|
@ -27,7 +27,8 @@ class SendGridEmailLogger(BaseEmailLogger):
|
|||
- SENDGRID_API_KEY
|
||||
"""
|
||||
|
||||
def __init__(self):
|
||||
def __init__(self, internal_usage_cache=None, **kwargs):
|
||||
super().__init__(internal_usage_cache=internal_usage_cache, **kwargs)
|
||||
self.async_httpx_client = get_async_httpx_client(
|
||||
llm_provider=httpxSpecialProvider.LoggingCallback
|
||||
)
|
||||
|
|
|
|||
|
|
@ -21,7 +21,8 @@ class SMTPEmailLogger(BaseEmailLogger):
|
|||
- SMTP_SENDER_EMAIL
|
||||
"""
|
||||
|
||||
def __init__(self):
|
||||
def __init__(self, internal_usage_cache=None, **kwargs):
|
||||
super().__init__(internal_usage_cache=internal_usage_cache, **kwargs)
|
||||
verbose_logger.debug("SMTP Email Logger initialized....")
|
||||
|
||||
async def send_email(
|
||||
|
|
|
|||
|
|
@ -0,0 +1,110 @@
|
|||
"""
|
||||
Polls LiteLLM_ManagedObjectTable to check if the response is complete.
|
||||
Cost tracking is handled automatically by litellm.aget_responses().
|
||||
"""
|
||||
|
||||
from typing import TYPE_CHECKING
|
||||
|
||||
import litellm
|
||||
from litellm._logging import verbose_proxy_logger
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from litellm.proxy.utils import PrismaClient, ProxyLogging
|
||||
from litellm.router import Router
|
||||
|
||||
|
||||
class CheckResponsesCost:
|
||||
def __init__(
|
||||
self,
|
||||
proxy_logging_obj: "ProxyLogging",
|
||||
prisma_client: "PrismaClient",
|
||||
llm_router: "Router",
|
||||
):
|
||||
from litellm.proxy.utils import PrismaClient, ProxyLogging
|
||||
from litellm.router import Router
|
||||
|
||||
self.proxy_logging_obj: ProxyLogging = proxy_logging_obj
|
||||
self.prisma_client: PrismaClient = prisma_client
|
||||
self.llm_router: Router = llm_router
|
||||
|
||||
async def check_responses_cost(self):
|
||||
"""
|
||||
Check if background responses are complete and track their cost.
|
||||
- Get all status="queued" or "in_progress" and file_purpose="response" jobs
|
||||
- Query the provider to check if response is complete
|
||||
- Cost is automatically tracked by litellm.aget_responses()
|
||||
- Mark completed/failed/cancelled responses as complete in the database
|
||||
"""
|
||||
jobs = await self.prisma_client.db.litellm_managedobjecttable.find_many(
|
||||
where={
|
||||
"status": {"in": ["queued", "in_progress"]},
|
||||
"file_purpose": "response",
|
||||
}
|
||||
)
|
||||
|
||||
verbose_proxy_logger.debug(f"Found {len(jobs)} response jobs to check")
|
||||
completed_jobs = []
|
||||
|
||||
for job in jobs:
|
||||
unified_object_id = job.unified_object_id
|
||||
|
||||
try:
|
||||
from litellm.proxy.hooks.responses_id_security import (
|
||||
ResponsesIDSecurity,
|
||||
)
|
||||
|
||||
# Get the stored response object to extract model information
|
||||
stored_response = job.file_object
|
||||
model_name = stored_response.get("model", None)
|
||||
|
||||
# Decrypt the response ID
|
||||
responses_id_security, _, _ = ResponsesIDSecurity()._decrypt_response_id(unified_object_id)
|
||||
|
||||
# Prepare metadata with model information for cost tracking
|
||||
litellm_metadata = {
|
||||
"user_api_key_user_id": job.created_by or "default-user-id",
|
||||
}
|
||||
|
||||
# Add model information if available
|
||||
if model_name:
|
||||
litellm_metadata["model"] = model_name
|
||||
litellm_metadata["model_group"] = model_name # Use same value for model_group
|
||||
|
||||
response = await litellm.aget_responses(
|
||||
response_id=responses_id_security,
|
||||
litellm_metadata=litellm_metadata,
|
||||
)
|
||||
|
||||
verbose_proxy_logger.debug(
|
||||
f"Response {unified_object_id} status: {response.status}, model: {model_name}"
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
verbose_proxy_logger.info(
|
||||
f"Skipping job {unified_object_id} due to error: {e}"
|
||||
)
|
||||
continue
|
||||
|
||||
# Check if response is in a terminal state
|
||||
if response.status == "completed":
|
||||
verbose_proxy_logger.info(
|
||||
f"Response {unified_object_id} is complete. Cost automatically tracked by aget_responses."
|
||||
)
|
||||
completed_jobs.append(job)
|
||||
|
||||
elif response.status in ["failed", "cancelled"]:
|
||||
verbose_proxy_logger.info(
|
||||
f"Response {unified_object_id} has status {response.status}, marking as complete"
|
||||
)
|
||||
completed_jobs.append(job)
|
||||
|
||||
# Mark completed jobs in the database
|
||||
if len(completed_jobs) > 0:
|
||||
await self.prisma_client.db.litellm_managedobjecttable.update_many(
|
||||
where={"id": {"in": [job.id for job in completed_jobs]}},
|
||||
data={"status": "completed"},
|
||||
)
|
||||
verbose_proxy_logger.info(
|
||||
f"Marked {len(completed_jobs)} response jobs as completed"
|
||||
)
|
||||
|
||||
|
|
@ -23,7 +23,9 @@ from litellm.proxy._types import (
|
|||
from litellm.proxy.openai_files_endpoints.common_utils import (
|
||||
_is_base64_encoded_unified_file_id,
|
||||
get_batch_id_from_unified_batch_id,
|
||||
get_content_type_from_file_object,
|
||||
get_model_id_from_unified_batch_id,
|
||||
normalize_mime_type_for_provider,
|
||||
)
|
||||
from litellm.types.llms.openai import (
|
||||
AllMessageValues,
|
||||
|
|
@ -33,6 +35,7 @@ from litellm.types.llms.openai import (
|
|||
FileObject,
|
||||
OpenAIFileObject,
|
||||
OpenAIFilesPurpose,
|
||||
ResponsesAPIResponse,
|
||||
)
|
||||
from litellm.types.utils import (
|
||||
CallTypesLiteral,
|
||||
|
|
@ -41,10 +44,6 @@ from litellm.types.utils import (
|
|||
LLMResponseTypes,
|
||||
SpecialEnums,
|
||||
)
|
||||
from litellm.proxy.openai_files_endpoints.common_utils import (
|
||||
get_content_type_from_file_object,
|
||||
normalize_mime_type_for_provider,
|
||||
)
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from litellm.types.llms.openai import HttpxBinaryResponseContent
|
||||
|
|
@ -133,10 +132,10 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
async def store_unified_object_id(
|
||||
self,
|
||||
unified_object_id: str,
|
||||
file_object: Union[LiteLLMBatch, LiteLLMFineTuningJob],
|
||||
file_object: Union[LiteLLMBatch, LiteLLMFineTuningJob, "ResponsesAPIResponse"],
|
||||
litellm_parent_otel_span: Optional[Span],
|
||||
model_object_id: str,
|
||||
file_purpose: Literal["batch", "fine-tune"],
|
||||
file_purpose: Literal["batch", "fine-tune", "response"],
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
) -> None:
|
||||
verbose_logger.info(
|
||||
|
|
@ -946,7 +945,9 @@ class _PROXY_LiteLLMManagedFiles(CustomLogger, BaseFileEndpoints):
|
|||
|
||||
# File is stored in a storage backend, download and convert to base64
|
||||
try:
|
||||
from litellm.llms.base_llm.files.storage_backend_factory import get_storage_backend
|
||||
from litellm.llms.base_llm.files.storage_backend_factory import (
|
||||
get_storage_backend,
|
||||
)
|
||||
|
||||
storage_backend_name = db_file.storage_backend
|
||||
storage_url = db_file.storage_url
|
||||
|
|
|
|||
|
|
@ -36,6 +36,8 @@ class EmailEvent(str, enum.Enum):
|
|||
virtual_key_created = "Virtual Key Created"
|
||||
new_user_invitation = "New User Invitation"
|
||||
virtual_key_rotated = "Virtual Key Rotated"
|
||||
soft_budget_crossed = "Soft Budget Crossed"
|
||||
max_budget_alert = "Max Budget Alert"
|
||||
|
||||
class EmailEventSettings(BaseModel):
|
||||
event: EmailEvent
|
||||
|
|
@ -51,6 +53,8 @@ class DefaultEmailSettings(BaseModel):
|
|||
EmailEvent.virtual_key_created: True, # On by default
|
||||
EmailEvent.new_user_invitation: True, # On by default
|
||||
EmailEvent.virtual_key_rotated: True, # On by default
|
||||
EmailEvent.soft_budget_crossed: True, # On by default
|
||||
EmailEvent.max_budget_alert: True, # On by default
|
||||
}
|
||||
)
|
||||
def to_dict(self) -> Dict[str, bool]:
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "litellm-enterprise"
|
||||
version = "0.1.25"
|
||||
version = "0.1.27"
|
||||
description = "Package for LiteLLM Enterprise features"
|
||||
authors = ["BerriAI"]
|
||||
readme = "README.md"
|
||||
|
|
@ -22,7 +22,7 @@ requires = ["poetry-core"]
|
|||
build-backend = "poetry.core.masonry.api"
|
||||
|
||||
[tool.commitizen]
|
||||
version = "0.1.25"
|
||||
version = "0.1.27"
|
||||
version_files = [
|
||||
"pyproject.toml:version",
|
||||
"../requirements.txt:litellm-enterprise==",
|
||||
|
|
|
|||
|
|
@ -0,0 +1,20 @@
|
|||
-- CreateTable
|
||||
CREATE TABLE "LiteLLM_SkillsTable" (
|
||||
"skill_id" TEXT NOT NULL,
|
||||
"display_title" TEXT,
|
||||
"description" TEXT,
|
||||
"instructions" TEXT,
|
||||
"source" TEXT NOT NULL DEFAULT 'custom',
|
||||
"latest_version" TEXT,
|
||||
"file_content" BYTEA,
|
||||
"file_name" TEXT,
|
||||
"file_type" TEXT,
|
||||
"metadata" JSONB DEFAULT '{}',
|
||||
"created_at" TIMESTAMP(3) NOT NULL DEFAULT CURRENT_TIMESTAMP,
|
||||
"created_by" TEXT,
|
||||
"updated_at" TIMESTAMP(3) NOT NULL DEFAULT CURRENT_TIMESTAMP,
|
||||
"updated_by" TEXT,
|
||||
|
||||
CONSTRAINT "LiteLLM_SkillsTable_pkey" PRIMARY KEY ("skill_id")
|
||||
);
|
||||
|
||||
|
|
@ -727,4 +727,22 @@ model LiteLLM_UISettings {
|
|||
ui_settings Json
|
||||
created_at DateTime @default(now())
|
||||
updated_at DateTime @updatedAt
|
||||
}
|
||||
|
||||
// Skills table for storing LiteLLM-managed skills
|
||||
model LiteLLM_SkillsTable {
|
||||
skill_id String @id @default(uuid())
|
||||
display_title String?
|
||||
description String?
|
||||
instructions String? // The skill instructions/prompt (from SKILL.md)
|
||||
source String @default("custom") // "custom" or "anthropic"
|
||||
latest_version String?
|
||||
file_content Bytes? // Binary content of the skill files (zip)
|
||||
file_name String? // Original filename
|
||||
file_type String? // MIME type (e.g., "application/zip")
|
||||
metadata Json? @default("{}")
|
||||
created_at DateTime @default(now())
|
||||
created_by String?
|
||||
updated_at DateTime @default(now()) @updatedAt
|
||||
updated_by String?
|
||||
}
|
||||
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "litellm-proxy-extras"
|
||||
version = "0.4.14"
|
||||
version = "0.4.16"
|
||||
description = "Additional files for the LiteLLM Proxy. Reduces the size of the main litellm package."
|
||||
authors = ["BerriAI"]
|
||||
readme = "README.md"
|
||||
|
|
@ -22,7 +22,7 @@ requires = ["poetry-core"]
|
|||
build-backend = "poetry.core.masonry.api"
|
||||
|
||||
[tool.commitizen]
|
||||
version = "0.4.14"
|
||||
version = "0.4.16"
|
||||
version_files = [
|
||||
"pyproject.toml:version",
|
||||
"../requirements.txt:litellm-proxy-extras==",
|
||||
|
|
|
|||
|
|
@ -134,6 +134,7 @@ _custom_logger_compatible_callbacks_literal = Literal[
|
|||
"weave_otel",
|
||||
"pagerduty",
|
||||
"humanloop",
|
||||
"azure_sentinel",
|
||||
"gcs_pubsub",
|
||||
"agentops",
|
||||
"anthropic_cache_control_hook",
|
||||
|
|
@ -557,6 +558,8 @@ ovhcloud_embedding_models: Set = set()
|
|||
lemonade_models: Set = set()
|
||||
docker_model_runner_models: Set = set()
|
||||
amazon_nova_models: Set = set()
|
||||
stability_models: Set = set()
|
||||
github_copilot_models: Set = set()
|
||||
|
||||
|
||||
def is_bedrock_pricing_only_model(key: str) -> bool:
|
||||
|
|
@ -801,6 +804,10 @@ def add_known_models():
|
|||
docker_model_runner_models.add(key)
|
||||
elif value.get("litellm_provider") == "amazon_nova":
|
||||
amazon_nova_models.add(key)
|
||||
elif value.get("litellm_provider") == "stability":
|
||||
stability_models.add(key)
|
||||
elif value.get("litellm_provider") == "github_copilot":
|
||||
github_copilot_models.add(key)
|
||||
|
||||
|
||||
add_known_models()
|
||||
|
|
@ -1003,6 +1010,8 @@ models_by_provider: dict = {
|
|||
"lemonade": lemonade_models,
|
||||
"clarifai": clarifai_models,
|
||||
"amazon_nova": amazon_nova_models,
|
||||
"stability": stability_models,
|
||||
"github_copilot": github_copilot_models,
|
||||
}
|
||||
|
||||
# mapping for those models which have larger equivalents
|
||||
|
|
@ -1054,47 +1063,8 @@ from .utils import client
|
|||
# Note: Most other utils imports are lazy-loaded via __getattr__ to avoid loading utils.py
|
||||
# (which imports tiktoken) at import time
|
||||
|
||||
from .llms.bytez.chat.transformation import BytezChatConfig
|
||||
from .llms.custom_llm import CustomLLM
|
||||
from .llms.aiohttp_openai.chat.transformation import AiohttpOpenAIChatConfig
|
||||
from .llms.galadriel.chat.transformation import GaladrielChatConfig
|
||||
from .llms.github.chat.transformation import GithubChatConfig
|
||||
from .llms.compactifai.chat.transformation import CompactifAIChatConfig
|
||||
from .llms.empower.chat.transformation import EmpowerChatConfig
|
||||
from .llms.huggingface.chat.transformation import HuggingFaceChatConfig
|
||||
from .llms.huggingface.embedding.transformation import HuggingFaceEmbeddingConfig
|
||||
from .llms.oobabooga.chat.transformation import OobaboogaConfig
|
||||
from .llms.maritalk import MaritalkConfig
|
||||
from .llms.openrouter.chat.transformation import OpenrouterConfig
|
||||
from .llms.datarobot.chat.transformation import DataRobotConfig
|
||||
from .llms.anthropic.chat.transformation import AnthropicConfig
|
||||
from .llms.anthropic.common_utils import AnthropicModelInfo
|
||||
from .llms.azure_ai.anthropic.transformation import AzureAnthropicConfig
|
||||
from .llms.groq.stt.transformation import GroqSTTConfig
|
||||
from .llms.anthropic.completion.transformation import AnthropicTextConfig
|
||||
from .llms.triton.completion.transformation import TritonConfig
|
||||
from .llms.triton.completion.transformation import TritonGenerateConfig
|
||||
from .llms.triton.completion.transformation import TritonInferConfig
|
||||
from .llms.triton.embedding.transformation import TritonEmbeddingConfig
|
||||
from .llms.huggingface.rerank.transformation import HuggingFaceRerankConfig
|
||||
from .llms.databricks.chat.transformation import DatabricksConfig
|
||||
from .llms.databricks.embed.transformation import DatabricksEmbeddingConfig
|
||||
from .llms.predibase.chat.transformation import PredibaseConfig
|
||||
from .llms.replicate.chat.transformation import ReplicateConfig
|
||||
from .llms.snowflake.chat.transformation import SnowflakeConfig
|
||||
from .llms.cohere.rerank.transformation import CohereRerankConfig
|
||||
from .llms.cohere.rerank_v2.transformation import CohereRerankV2Config
|
||||
from .llms.azure_ai.rerank.transformation import AzureAIRerankConfig
|
||||
from .llms.infinity.rerank.transformation import InfinityRerankConfig
|
||||
from .llms.jina_ai.rerank.transformation import JinaAIRerankConfig
|
||||
from .llms.deepinfra.rerank.transformation import DeepinfraRerankConfig
|
||||
from .llms.hosted_vllm.rerank.transformation import HostedVLLMRerankConfig
|
||||
from .llms.nvidia_nim.rerank.transformation import NvidiaNimRerankConfig
|
||||
from .llms.nvidia_nim.rerank.ranking_transformation import NvidiaNimRankingConfig
|
||||
from .llms.vertex_ai.rerank.transformation import VertexAIRerankConfig
|
||||
from .llms.fireworks_ai.rerank.transformation import FireworksAIRerankConfig
|
||||
from .llms.voyage.rerank.transformation import VoyageRerankConfig
|
||||
from .llms.clarifai.chat.transformation import ClarifaiConfig
|
||||
from .llms.ai21.chat.transformation import AI21ChatConfig, AI21ChatConfig as AI21Config
|
||||
from .llms.meta_llama.chat.transformation import LlamaAPIConfig
|
||||
from .llms.anthropic.experimental_pass_through.messages.transformation import (
|
||||
|
|
@ -1194,9 +1164,9 @@ from .llms.bedrock.chat.invoke_transformations.amazon_openai_transformation impo
|
|||
AmazonBedrockOpenAIConfig,
|
||||
)
|
||||
|
||||
from .llms.bedrock.image.amazon_stability1_transformation import AmazonStabilityConfig
|
||||
from .llms.bedrock.image.amazon_stability3_transformation import AmazonStability3Config
|
||||
from .llms.bedrock.image.amazon_nova_canvas_transformation import AmazonNovaCanvasConfig
|
||||
from .llms.bedrock.image_generation.amazon_stability1_transformation import AmazonStabilityConfig
|
||||
from .llms.bedrock.image_generation.amazon_stability3_transformation import AmazonStability3Config
|
||||
from .llms.bedrock.image_generation.amazon_nova_canvas_transformation import AmazonNovaCanvasConfig
|
||||
from .llms.bedrock.embed.amazon_titan_g1_transformation import AmazonTitanG1Config
|
||||
from .llms.bedrock.embed.amazon_titan_multimodal_transformation import (
|
||||
AmazonTitanMultimodalEmbeddingG1Config,
|
||||
|
|
@ -1502,6 +1472,50 @@ if TYPE_CHECKING:
|
|||
from litellm.types.utils import ModelInfo as _ModelInfoType
|
||||
from litellm.llms.custom_httpx.http_handler import AsyncHTTPHandler, HTTPHandler
|
||||
from litellm.caching.caching import Cache
|
||||
|
||||
# Type stubs for lazy-loaded configs to help mypy
|
||||
from .llms.bedrock.chat.converse_transformation import AmazonConverseConfig as AmazonConverseConfig
|
||||
from .llms.openai_like.chat.handler import OpenAILikeChatConfig as OpenAILikeChatConfig
|
||||
from .llms.galadriel.chat.transformation import GaladrielChatConfig as GaladrielChatConfig
|
||||
from .llms.github.chat.transformation import GithubChatConfig as GithubChatConfig
|
||||
from .llms.azure_ai.anthropic.transformation import AzureAnthropicConfig as AzureAnthropicConfig
|
||||
from .llms.bytez.chat.transformation import BytezChatConfig as BytezChatConfig
|
||||
from .llms.compactifai.chat.transformation import CompactifAIChatConfig as CompactifAIChatConfig
|
||||
from .llms.empower.chat.transformation import EmpowerChatConfig as EmpowerChatConfig
|
||||
from .llms.aiohttp_openai.chat.transformation import AiohttpOpenAIChatConfig as AiohttpOpenAIChatConfig
|
||||
from .llms.huggingface.chat.transformation import HuggingFaceChatConfig as HuggingFaceChatConfig
|
||||
from .llms.huggingface.embedding.transformation import HuggingFaceEmbeddingConfig as HuggingFaceEmbeddingConfig
|
||||
from .llms.oobabooga.chat.transformation import OobaboogaConfig as OobaboogaConfig
|
||||
from .llms.maritalk import MaritalkConfig as MaritalkConfig
|
||||
from .llms.openrouter.chat.transformation import OpenrouterConfig as OpenrouterConfig
|
||||
from .llms.datarobot.chat.transformation import DataRobotConfig as DataRobotConfig
|
||||
from .llms.anthropic.chat.transformation import AnthropicConfig as AnthropicConfig
|
||||
from .llms.anthropic.completion.transformation import AnthropicTextConfig as AnthropicTextConfig
|
||||
from .llms.groq.stt.transformation import GroqSTTConfig as GroqSTTConfig
|
||||
from .llms.triton.completion.transformation import TritonConfig as TritonConfig
|
||||
from .llms.triton.completion.transformation import TritonGenerateConfig as TritonGenerateConfig
|
||||
from .llms.triton.completion.transformation import TritonInferConfig as TritonInferConfig
|
||||
from .llms.triton.embedding.transformation import TritonEmbeddingConfig as TritonEmbeddingConfig
|
||||
from .llms.huggingface.rerank.transformation import HuggingFaceRerankConfig as HuggingFaceRerankConfig
|
||||
from .llms.databricks.chat.transformation import DatabricksConfig as DatabricksConfig
|
||||
from .llms.databricks.embed.transformation import DatabricksEmbeddingConfig as DatabricksEmbeddingConfig
|
||||
from .llms.predibase.chat.transformation import PredibaseConfig as PredibaseConfig
|
||||
from .llms.replicate.chat.transformation import ReplicateConfig as ReplicateConfig
|
||||
from .llms.snowflake.chat.transformation import SnowflakeConfig as SnowflakeConfig
|
||||
from .llms.cohere.rerank.transformation import CohereRerankConfig as CohereRerankConfig
|
||||
from .llms.cohere.rerank_v2.transformation import CohereRerankV2Config as CohereRerankV2Config
|
||||
from .llms.azure_ai.rerank.transformation import AzureAIRerankConfig as AzureAIRerankConfig
|
||||
from .llms.infinity.rerank.transformation import InfinityRerankConfig as InfinityRerankConfig
|
||||
from .llms.jina_ai.rerank.transformation import JinaAIRerankConfig as JinaAIRerankConfig
|
||||
from .llms.deepinfra.rerank.transformation import DeepinfraRerankConfig as DeepinfraRerankConfig
|
||||
from .llms.hosted_vllm.rerank.transformation import HostedVLLMRerankConfig as HostedVLLMRerankConfig
|
||||
from .llms.nvidia_nim.rerank.transformation import NvidiaNimRerankConfig as NvidiaNimRerankConfig
|
||||
from .llms.nvidia_nim.rerank.ranking_transformation import NvidiaNimRankingConfig as NvidiaNimRankingConfig
|
||||
from .llms.vertex_ai.rerank.transformation import VertexAIRerankConfig as VertexAIRerankConfig
|
||||
from .llms.fireworks_ai.rerank.transformation import FireworksAIRerankConfig as FireworksAIRerankConfig
|
||||
from .llms.voyage.rerank.transformation import VoyageRerankConfig as VoyageRerankConfig
|
||||
from .llms.clarifai.chat.transformation import ClarifaiConfig as ClarifaiConfig
|
||||
from .llms.ai21.chat.transformation import AI21ChatConfig as AI21ChatConfig
|
||||
from litellm.caching.llm_caching_handler import LLMClientCache
|
||||
from litellm.types.llms.bedrock import COHERE_EMBEDDING_INPUT_TYPES
|
||||
from litellm.types.utils import (
|
||||
|
|
@ -1555,9 +1569,7 @@ if TYPE_CHECKING:
|
|||
module_level_aclient: AsyncHTTPHandler
|
||||
module_level_client: HTTPHandler
|
||||
|
||||
# LLM config classes - lazy loaded only
|
||||
AmazonConverseConfig: Type[Any]
|
||||
OpenAILikeChatConfig: Type[Any]
|
||||
# Note: AmazonConverseConfig and OpenAILikeChatConfig are imported above in TYPE_CHECKING block
|
||||
|
||||
|
||||
def __getattr__(name: str) -> Any:
|
||||
|
|
|
|||
|
|
@ -1,5 +1,6 @@
|
|||
from typing import Any, Optional, cast
|
||||
import sys
|
||||
from typing import Any, Optional, cast
|
||||
|
||||
|
||||
def _get_litellm_globals() -> dict:
|
||||
"""Helper to get the globals dictionary of the litellm module."""
|
||||
|
|
@ -158,6 +159,45 @@ DOTPROMPT_NAMES = (
|
|||
LLM_CONFIG_NAMES = (
|
||||
"AmazonConverseConfig",
|
||||
"OpenAILikeChatConfig",
|
||||
"GaladrielChatConfig",
|
||||
"GithubChatConfig",
|
||||
"AzureAnthropicConfig",
|
||||
"BytezChatConfig",
|
||||
"CompactifAIChatConfig",
|
||||
"EmpowerChatConfig",
|
||||
"AiohttpOpenAIChatConfig",
|
||||
"HuggingFaceChatConfig",
|
||||
"HuggingFaceEmbeddingConfig",
|
||||
"OobaboogaConfig",
|
||||
"MaritalkConfig",
|
||||
"OpenrouterConfig",
|
||||
"DataRobotConfig",
|
||||
"AnthropicConfig",
|
||||
"AnthropicTextConfig",
|
||||
"GroqSTTConfig",
|
||||
"TritonConfig",
|
||||
"TritonGenerateConfig",
|
||||
"TritonInferConfig",
|
||||
"TritonEmbeddingConfig",
|
||||
"HuggingFaceRerankConfig",
|
||||
"DatabricksConfig",
|
||||
"DatabricksEmbeddingConfig",
|
||||
"PredibaseConfig",
|
||||
"ReplicateConfig",
|
||||
"SnowflakeConfig",
|
||||
"CohereRerankConfig",
|
||||
"CohereRerankV2Config",
|
||||
"AzureAIRerankConfig",
|
||||
"InfinityRerankConfig",
|
||||
"JinaAIRerankConfig",
|
||||
"DeepinfraRerankConfig",
|
||||
"HostedVLLMRerankConfig",
|
||||
"NvidiaNimRerankConfig",
|
||||
"NvidiaNimRankingConfig",
|
||||
"VertexAIRerankConfig",
|
||||
"FireworksAIRerankConfig",
|
||||
"VoyageRerankConfig",
|
||||
"ClarifaiConfig",
|
||||
)
|
||||
|
||||
# Types that support lazy loading via _lazy_import_types
|
||||
|
|
@ -223,7 +263,9 @@ def _lazy_import_utils(name: str) -> Any: # noqa: PLR0915
|
|||
return _supports_response_schema
|
||||
|
||||
if name == "supports_parallel_function_calling":
|
||||
from .utils import supports_parallel_function_calling as _supports_parallel_function_calling
|
||||
from .utils import (
|
||||
supports_parallel_function_calling as _supports_parallel_function_calling,
|
||||
)
|
||||
_globals["supports_parallel_function_calling"] = _supports_parallel_function_calling
|
||||
return _supports_parallel_function_calling
|
||||
|
||||
|
|
@ -389,7 +431,9 @@ def _lazy_import_cost_calculator(name: str) -> Any:
|
|||
return _cost_per_token
|
||||
|
||||
if name == "response_cost_calculator":
|
||||
from .cost_calculator import response_cost_calculator as _response_cost_calculator
|
||||
from .cost_calculator import (
|
||||
response_cost_calculator as _response_cost_calculator,
|
||||
)
|
||||
_globals["response_cost_calculator"] = _response_cost_calculator
|
||||
return _response_cost_calculator
|
||||
|
||||
|
|
@ -461,9 +505,7 @@ def _lazy_import_types_utils(name: str) -> Any:
|
|||
return _CredentialItem
|
||||
|
||||
if name == "PriorityReservationDict":
|
||||
from .types.utils import (
|
||||
PriorityReservationDict as _PriorityReservationDict,
|
||||
)
|
||||
from .types.utils import PriorityReservationDict as _PriorityReservationDict
|
||||
|
||||
_globals["PriorityReservationDict"] = _PriorityReservationDict
|
||||
return _PriorityReservationDict
|
||||
|
|
@ -483,9 +525,7 @@ def _lazy_import_types_utils(name: str) -> Any:
|
|||
return _SearchProviders
|
||||
|
||||
if name == "GenericStreamingChunk":
|
||||
from .types.utils import (
|
||||
GenericStreamingChunk as _GenericStreamingChunk,
|
||||
)
|
||||
from .types.utils import GenericStreamingChunk as _GenericStreamingChunk
|
||||
|
||||
_globals["GenericStreamingChunk"] = _GenericStreamingChunk
|
||||
return _GenericStreamingChunk
|
||||
|
|
@ -529,13 +569,17 @@ def _lazy_import_llm_client_cache(name: str) -> Any:
|
|||
_globals = _get_litellm_globals()
|
||||
|
||||
if name == "LLMClientCache":
|
||||
from litellm.caching.llm_caching_handler import LLMClientCache as _LLMClientCache
|
||||
from litellm.caching.llm_caching_handler import (
|
||||
LLMClientCache as _LLMClientCache,
|
||||
)
|
||||
|
||||
_globals["LLMClientCache"] = _LLMClientCache
|
||||
return _LLMClientCache
|
||||
|
||||
if name == "in_memory_llm_clients_cache":
|
||||
from litellm.caching.llm_caching_handler import LLMClientCache as _LLMClientCache
|
||||
from litellm.caching.llm_caching_handler import (
|
||||
LLMClientCache as _LLMClientCache,
|
||||
)
|
||||
|
||||
instance = _LLMClientCache()
|
||||
# Only populate the requested singleton name to keep lazy-import
|
||||
|
|
@ -555,7 +599,9 @@ def _lazy_import_litellm_logging(name: str) -> Any:
|
|||
return _Logging
|
||||
|
||||
if name == "modify_integration":
|
||||
from litellm.litellm_core_utils.litellm_logging import modify_integration as _modify_integration
|
||||
from litellm.litellm_core_utils.litellm_logging import (
|
||||
modify_integration as _modify_integration,
|
||||
)
|
||||
_globals["modify_integration"] = _modify_integration
|
||||
return _modify_integration
|
||||
|
||||
|
|
@ -630,9 +676,7 @@ def _lazy_import_types(name: str) -> Any:
|
|||
_globals = _get_litellm_globals()
|
||||
|
||||
if name == "GuardrailItem":
|
||||
from litellm.types.guardrails import (
|
||||
GuardrailItem as _GuardrailItem,
|
||||
)
|
||||
from litellm.types.guardrails import GuardrailItem as _GuardrailItem
|
||||
|
||||
_globals["GuardrailItem"] = _GuardrailItem
|
||||
return _GuardrailItem
|
||||
|
|
@ -640,7 +684,7 @@ def _lazy_import_types(name: str) -> Any:
|
|||
raise AttributeError(f"Types lazy import: unknown attribute {name!r}")
|
||||
|
||||
|
||||
def _lazy_import_llm_configs(name: str) -> Any:
|
||||
def _lazy_import_llm_configs(name: str) -> Any: # noqa: PLR0915
|
||||
"""Lazy import for LLM config classes."""
|
||||
_globals = _get_litellm_globals()
|
||||
|
||||
|
|
@ -660,4 +704,306 @@ def _lazy_import_llm_configs(name: str) -> Any:
|
|||
_globals["OpenAILikeChatConfig"] = _OpenAILikeChatConfig
|
||||
return _OpenAILikeChatConfig
|
||||
|
||||
if name == "GaladrielChatConfig":
|
||||
from .llms.galadriel.chat.transformation import (
|
||||
GaladrielChatConfig as _GaladrielChatConfig,
|
||||
)
|
||||
|
||||
_globals["GaladrielChatConfig"] = _GaladrielChatConfig
|
||||
return _GaladrielChatConfig
|
||||
|
||||
if name == "GithubChatConfig":
|
||||
from .llms.github.chat.transformation import (
|
||||
GithubChatConfig as _GithubChatConfig,
|
||||
)
|
||||
|
||||
_globals["GithubChatConfig"] = _GithubChatConfig
|
||||
return _GithubChatConfig
|
||||
|
||||
if name == "AzureAnthropicConfig":
|
||||
from .llms.azure_ai.anthropic.transformation import (
|
||||
AzureAnthropicConfig as _AzureAnthropicConfig,
|
||||
)
|
||||
|
||||
_globals["AzureAnthropicConfig"] = _AzureAnthropicConfig
|
||||
return _AzureAnthropicConfig
|
||||
|
||||
if name == "BytezChatConfig":
|
||||
from .llms.bytez.chat.transformation import BytezChatConfig as _BytezChatConfig
|
||||
|
||||
_globals["BytezChatConfig"] = _BytezChatConfig
|
||||
return _BytezChatConfig
|
||||
|
||||
if name == "CompactifAIChatConfig":
|
||||
from .llms.compactifai.chat.transformation import (
|
||||
CompactifAIChatConfig as _CompactifAIChatConfig,
|
||||
)
|
||||
|
||||
_globals["CompactifAIChatConfig"] = _CompactifAIChatConfig
|
||||
return _CompactifAIChatConfig
|
||||
|
||||
if name == "EmpowerChatConfig":
|
||||
from .llms.empower.chat.transformation import (
|
||||
EmpowerChatConfig as _EmpowerChatConfig,
|
||||
)
|
||||
|
||||
_globals["EmpowerChatConfig"] = _EmpowerChatConfig
|
||||
return _EmpowerChatConfig
|
||||
|
||||
if name == "AiohttpOpenAIChatConfig":
|
||||
from .llms.aiohttp_openai.chat.transformation import (
|
||||
AiohttpOpenAIChatConfig as _AiohttpOpenAIChatConfig,
|
||||
)
|
||||
|
||||
_globals["AiohttpOpenAIChatConfig"] = _AiohttpOpenAIChatConfig
|
||||
return _AiohttpOpenAIChatConfig
|
||||
|
||||
if name == "HuggingFaceChatConfig":
|
||||
from .llms.huggingface.chat.transformation import (
|
||||
HuggingFaceChatConfig as _HuggingFaceChatConfig,
|
||||
)
|
||||
|
||||
_globals["HuggingFaceChatConfig"] = _HuggingFaceChatConfig
|
||||
return _HuggingFaceChatConfig
|
||||
|
||||
if name == "HuggingFaceEmbeddingConfig":
|
||||
from .llms.huggingface.embedding.transformation import (
|
||||
HuggingFaceEmbeddingConfig as _HuggingFaceEmbeddingConfig,
|
||||
)
|
||||
|
||||
_globals["HuggingFaceEmbeddingConfig"] = _HuggingFaceEmbeddingConfig
|
||||
return _HuggingFaceEmbeddingConfig
|
||||
|
||||
if name == "OobaboogaConfig":
|
||||
from .llms.oobabooga.chat.transformation import (
|
||||
OobaboogaConfig as _OobaboogaConfig,
|
||||
)
|
||||
|
||||
_globals["OobaboogaConfig"] = _OobaboogaConfig
|
||||
return _OobaboogaConfig
|
||||
|
||||
if name == "MaritalkConfig":
|
||||
from .llms.maritalk import MaritalkConfig as _MaritalkConfig
|
||||
|
||||
_globals["MaritalkConfig"] = _MaritalkConfig
|
||||
return _MaritalkConfig
|
||||
|
||||
if name == "OpenrouterConfig":
|
||||
from .llms.openrouter.chat.transformation import (
|
||||
OpenrouterConfig as _OpenrouterConfig,
|
||||
)
|
||||
|
||||
_globals["OpenrouterConfig"] = _OpenrouterConfig
|
||||
return _OpenrouterConfig
|
||||
|
||||
if name == "DataRobotConfig":
|
||||
from .llms.datarobot.chat.transformation import (
|
||||
DataRobotConfig as _DataRobotConfig,
|
||||
)
|
||||
|
||||
_globals["DataRobotConfig"] = _DataRobotConfig
|
||||
return _DataRobotConfig
|
||||
|
||||
if name == "AnthropicConfig":
|
||||
from .llms.anthropic.chat.transformation import (
|
||||
AnthropicConfig as _AnthropicConfig,
|
||||
)
|
||||
|
||||
_globals["AnthropicConfig"] = _AnthropicConfig
|
||||
return _AnthropicConfig
|
||||
|
||||
if name == "AnthropicTextConfig":
|
||||
from .llms.anthropic.completion.transformation import (
|
||||
AnthropicTextConfig as _AnthropicTextConfig,
|
||||
)
|
||||
|
||||
_globals["AnthropicTextConfig"] = _AnthropicTextConfig
|
||||
return _AnthropicTextConfig
|
||||
|
||||
if name == "GroqSTTConfig":
|
||||
from .llms.groq.stt.transformation import GroqSTTConfig as _GroqSTTConfig
|
||||
|
||||
_globals["GroqSTTConfig"] = _GroqSTTConfig
|
||||
return _GroqSTTConfig
|
||||
|
||||
if name == "TritonConfig":
|
||||
from .llms.triton.completion.transformation import TritonConfig as _TritonConfig
|
||||
|
||||
_globals["TritonConfig"] = _TritonConfig
|
||||
return _TritonConfig
|
||||
|
||||
if name == "TritonGenerateConfig":
|
||||
from .llms.triton.completion.transformation import (
|
||||
TritonGenerateConfig as _TritonGenerateConfig,
|
||||
)
|
||||
|
||||
_globals["TritonGenerateConfig"] = _TritonGenerateConfig
|
||||
return _TritonGenerateConfig
|
||||
|
||||
if name == "TritonInferConfig":
|
||||
from .llms.triton.completion.transformation import (
|
||||
TritonInferConfig as _TritonInferConfig,
|
||||
)
|
||||
|
||||
_globals["TritonInferConfig"] = _TritonInferConfig
|
||||
return _TritonInferConfig
|
||||
|
||||
if name == "TritonEmbeddingConfig":
|
||||
from .llms.triton.embedding.transformation import (
|
||||
TritonEmbeddingConfig as _TritonEmbeddingConfig,
|
||||
)
|
||||
|
||||
_globals["TritonEmbeddingConfig"] = _TritonEmbeddingConfig
|
||||
return _TritonEmbeddingConfig
|
||||
|
||||
if name == "HuggingFaceRerankConfig":
|
||||
from .llms.huggingface.rerank.transformation import (
|
||||
HuggingFaceRerankConfig as _HuggingFaceRerankConfig,
|
||||
)
|
||||
|
||||
_globals["HuggingFaceRerankConfig"] = _HuggingFaceRerankConfig
|
||||
return _HuggingFaceRerankConfig
|
||||
|
||||
if name == "DatabricksConfig":
|
||||
from .llms.databricks.chat.transformation import (
|
||||
DatabricksConfig as _DatabricksConfig,
|
||||
)
|
||||
|
||||
_globals["DatabricksConfig"] = _DatabricksConfig
|
||||
return _DatabricksConfig
|
||||
|
||||
if name == "DatabricksEmbeddingConfig":
|
||||
from .llms.databricks.embed.transformation import (
|
||||
DatabricksEmbeddingConfig as _DatabricksEmbeddingConfig,
|
||||
)
|
||||
|
||||
_globals["DatabricksEmbeddingConfig"] = _DatabricksEmbeddingConfig
|
||||
return _DatabricksEmbeddingConfig
|
||||
|
||||
if name == "PredibaseConfig":
|
||||
from .llms.predibase.chat.transformation import (
|
||||
PredibaseConfig as _PredibaseConfig,
|
||||
)
|
||||
|
||||
_globals["PredibaseConfig"] = _PredibaseConfig
|
||||
return _PredibaseConfig
|
||||
|
||||
if name == "ReplicateConfig":
|
||||
from .llms.replicate.chat.transformation import (
|
||||
ReplicateConfig as _ReplicateConfig,
|
||||
)
|
||||
|
||||
_globals["ReplicateConfig"] = _ReplicateConfig
|
||||
return _ReplicateConfig
|
||||
|
||||
if name == "SnowflakeConfig":
|
||||
from .llms.snowflake.chat.transformation import (
|
||||
SnowflakeConfig as _SnowflakeConfig,
|
||||
)
|
||||
|
||||
_globals["SnowflakeConfig"] = _SnowflakeConfig
|
||||
return _SnowflakeConfig
|
||||
|
||||
if name == "CohereRerankConfig":
|
||||
from .llms.cohere.rerank.transformation import (
|
||||
CohereRerankConfig as _CohereRerankConfig,
|
||||
)
|
||||
|
||||
_globals["CohereRerankConfig"] = _CohereRerankConfig
|
||||
return _CohereRerankConfig
|
||||
|
||||
if name == "CohereRerankV2Config":
|
||||
from .llms.cohere.rerank_v2.transformation import (
|
||||
CohereRerankV2Config as _CohereRerankV2Config,
|
||||
)
|
||||
|
||||
_globals["CohereRerankV2Config"] = _CohereRerankV2Config
|
||||
return _CohereRerankV2Config
|
||||
|
||||
if name == "AzureAIRerankConfig":
|
||||
from .llms.azure_ai.rerank.transformation import (
|
||||
AzureAIRerankConfig as _AzureAIRerankConfig,
|
||||
)
|
||||
|
||||
_globals["AzureAIRerankConfig"] = _AzureAIRerankConfig
|
||||
return _AzureAIRerankConfig
|
||||
|
||||
if name == "InfinityRerankConfig":
|
||||
from .llms.infinity.rerank.transformation import (
|
||||
InfinityRerankConfig as _InfinityRerankConfig,
|
||||
)
|
||||
|
||||
_globals["InfinityRerankConfig"] = _InfinityRerankConfig
|
||||
return _InfinityRerankConfig
|
||||
|
||||
if name == "JinaAIRerankConfig":
|
||||
from .llms.jina_ai.rerank.transformation import (
|
||||
JinaAIRerankConfig as _JinaAIRerankConfig,
|
||||
)
|
||||
|
||||
_globals["JinaAIRerankConfig"] = _JinaAIRerankConfig
|
||||
return _JinaAIRerankConfig
|
||||
|
||||
if name == "DeepinfraRerankConfig":
|
||||
from .llms.deepinfra.rerank.transformation import (
|
||||
DeepinfraRerankConfig as _DeepinfraRerankConfig,
|
||||
)
|
||||
|
||||
_globals["DeepinfraRerankConfig"] = _DeepinfraRerankConfig
|
||||
return _DeepinfraRerankConfig
|
||||
|
||||
if name == "HostedVLLMRerankConfig":
|
||||
from .llms.hosted_vllm.rerank.transformation import (
|
||||
HostedVLLMRerankConfig as _HostedVLLMRerankConfig,
|
||||
)
|
||||
|
||||
_globals["HostedVLLMRerankConfig"] = _HostedVLLMRerankConfig
|
||||
return _HostedVLLMRerankConfig
|
||||
|
||||
if name == "NvidiaNimRerankConfig":
|
||||
from .llms.nvidia_nim.rerank.transformation import (
|
||||
NvidiaNimRerankConfig as _NvidiaNimRerankConfig,
|
||||
)
|
||||
|
||||
_globals["NvidiaNimRerankConfig"] = _NvidiaNimRerankConfig
|
||||
return _NvidiaNimRerankConfig
|
||||
|
||||
if name == "NvidiaNimRankingConfig":
|
||||
from .llms.nvidia_nim.rerank.ranking_transformation import (
|
||||
NvidiaNimRankingConfig as _NvidiaNimRankingConfig,
|
||||
)
|
||||
|
||||
_globals["NvidiaNimRankingConfig"] = _NvidiaNimRankingConfig
|
||||
return _NvidiaNimRankingConfig
|
||||
|
||||
if name == "VertexAIRerankConfig":
|
||||
from .llms.vertex_ai.rerank.transformation import (
|
||||
VertexAIRerankConfig as _VertexAIRerankConfig,
|
||||
)
|
||||
|
||||
_globals["VertexAIRerankConfig"] = _VertexAIRerankConfig
|
||||
return _VertexAIRerankConfig
|
||||
|
||||
if name == "FireworksAIRerankConfig":
|
||||
from .llms.fireworks_ai.rerank.transformation import (
|
||||
FireworksAIRerankConfig as _FireworksAIRerankConfig,
|
||||
)
|
||||
|
||||
_globals["FireworksAIRerankConfig"] = _FireworksAIRerankConfig
|
||||
return _FireworksAIRerankConfig
|
||||
|
||||
if name == "VoyageRerankConfig":
|
||||
from .llms.voyage.rerank.transformation import (
|
||||
VoyageRerankConfig as _VoyageRerankConfig,
|
||||
)
|
||||
|
||||
_globals["VoyageRerankConfig"] = _VoyageRerankConfig
|
||||
return _VoyageRerankConfig
|
||||
|
||||
if name == "ClarifaiConfig":
|
||||
from .llms.clarifai.chat.transformation import ClarifaiConfig as _ClarifaiConfig
|
||||
|
||||
_globals["ClarifaiConfig"] = _ClarifaiConfig
|
||||
return _ClarifaiConfig
|
||||
|
||||
raise AttributeError(f"LLM config lazy import: unknown attribute {name!r}")
|
||||
|
|
@ -37,6 +37,7 @@ async def acreate(
|
|||
tools: Optional[List[Dict]] = None,
|
||||
top_k: Optional[int] = None,
|
||||
top_p: Optional[float] = None,
|
||||
container: Optional[Dict] = None,
|
||||
**kwargs
|
||||
) -> Union[AnthropicMessagesResponse, AsyncIterator]:
|
||||
"""
|
||||
|
|
@ -56,6 +57,7 @@ async def acreate(
|
|||
tools (List[Dict], optional): List of tool definitions
|
||||
top_k (int, optional): Top K sampling parameter
|
||||
top_p (float, optional): Nucleus sampling parameter
|
||||
container (Dict, optional): Container config with skills for code execution
|
||||
**kwargs: Additional arguments
|
||||
|
||||
Returns:
|
||||
|
|
@ -75,6 +77,7 @@ async def acreate(
|
|||
tools=tools,
|
||||
top_k=top_k,
|
||||
top_p=top_p,
|
||||
container=container,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
|
|
@ -93,6 +96,7 @@ def create(
|
|||
tools: Optional[List[Dict]] = None,
|
||||
top_k: Optional[int] = None,
|
||||
top_p: Optional[float] = None,
|
||||
container: Optional[Dict] = None,
|
||||
**kwargs
|
||||
) -> Union[
|
||||
AnthropicMessagesResponse,
|
||||
|
|
@ -135,5 +139,6 @@ def create(
|
|||
tools=tools,
|
||||
top_k=top_k,
|
||||
top_p=top_p,
|
||||
container=container,
|
||||
**kwargs,
|
||||
)
|
||||
|
|
|
|||
|
|
@ -10,6 +10,7 @@ Has 4 primary methods:
|
|||
|
||||
import ast
|
||||
import asyncio
|
||||
import hashlib
|
||||
import inspect
|
||||
import json
|
||||
import time
|
||||
|
|
@ -145,9 +146,17 @@ class RedisCache(BaseCache):
|
|||
except Exception:
|
||||
pass
|
||||
|
||||
### ASYNC HEALTH PING ###
|
||||
self._setup_health_pings()
|
||||
|
||||
if litellm.default_redis_ttl is not None:
|
||||
super().__init__(default_ttl=int(litellm.default_redis_ttl))
|
||||
else:
|
||||
super().__init__() # defaults to 60s
|
||||
|
||||
def _setup_health_pings(self):
|
||||
"""Setup async and sync health pings for Redis."""
|
||||
# ASYNC HEALTH PING
|
||||
try:
|
||||
# asyncio.get_running_loop().create_task(self.ping())
|
||||
_ = asyncio.get_running_loop().create_task(self.ping())
|
||||
except Exception as e:
|
||||
if "no running event loop" in str(e):
|
||||
|
|
@ -159,8 +168,9 @@ class RedisCache(BaseCache):
|
|||
"Error connecting to Async Redis client - {}".format(str(e)),
|
||||
extra={"error": str(e)},
|
||||
)
|
||||
self._handle_async_ping_error(e)
|
||||
|
||||
### SYNC HEALTH PING ###
|
||||
# SYNC HEALTH PING
|
||||
try:
|
||||
if hasattr(self.redis_client, "ping"):
|
||||
self.redis_client.ping() # type: ignore
|
||||
|
|
@ -168,11 +178,53 @@ class RedisCache(BaseCache):
|
|||
verbose_logger.error(
|
||||
"Error connecting to Sync Redis client", extra={"error": str(e)}
|
||||
)
|
||||
self._handle_sync_ping_error(e)
|
||||
|
||||
if litellm.default_redis_ttl is not None:
|
||||
super().__init__(default_ttl=int(litellm.default_redis_ttl))
|
||||
else:
|
||||
super().__init__() # defaults to 60s
|
||||
def _handle_async_ping_error(self, e: Exception):
|
||||
"""Handle async ping error with service failure hook."""
|
||||
try:
|
||||
loop = asyncio.get_running_loop()
|
||||
start_time = time.time()
|
||||
end_time = start_time
|
||||
loop.create_task(
|
||||
self.service_logger_obj.async_service_failure_hook(
|
||||
service=ServiceTypes.REDIS,
|
||||
duration=end_time - start_time,
|
||||
error=e,
|
||||
call_type="redis_async_ping",
|
||||
)
|
||||
)
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
def _handle_sync_ping_error(self, e: Exception):
|
||||
"""Handle sync ping error with service failure hook."""
|
||||
try:
|
||||
loop = asyncio.get_running_loop()
|
||||
start_time = time.time()
|
||||
end_time = start_time
|
||||
loop.create_task(
|
||||
self.service_logger_obj.async_service_failure_hook(
|
||||
service=ServiceTypes.REDIS,
|
||||
duration=end_time - start_time,
|
||||
error=e,
|
||||
call_type="redis_sync_ping",
|
||||
)
|
||||
)
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
def _get_async_client_cache_key(self) -> str:
|
||||
"""
|
||||
Generate a cache key for the async Redis client based on connection parameters.
|
||||
This ensures different Redis configurations use different cached clients.
|
||||
"""
|
||||
# Create a stable representation of redis_kwargs for hashing
|
||||
# Sort keys to ensure consistent hash regardless of parameter order
|
||||
sorted_kwargs = sorted(self.redis_kwargs.items())
|
||||
kwargs_str = json.dumps(sorted_kwargs, sort_keys=True)
|
||||
kwargs_hash = hashlib.sha256(kwargs_str.encode()).hexdigest()[:16]
|
||||
return f"async-redis-client-{kwargs_hash}"
|
||||
|
||||
def init_async_client(
|
||||
self,
|
||||
|
|
@ -181,7 +233,8 @@ class RedisCache(BaseCache):
|
|||
|
||||
from .._redis import get_redis_async_client, get_redis_connection_pool
|
||||
|
||||
cached_client = in_memory_llm_clients_cache.get_cache(key="async-redis-client")
|
||||
cache_key = self._get_async_client_cache_key()
|
||||
cached_client = in_memory_llm_clients_cache.get_cache(key=cache_key)
|
||||
if cached_client is not None:
|
||||
redis_async_client = cast(
|
||||
Union[async_redis_client, async_redis_cluster_client], cached_client
|
||||
|
|
@ -193,7 +246,7 @@ class RedisCache(BaseCache):
|
|||
connection_pool=self.async_redis_conn_pool, **self.redis_kwargs
|
||||
)
|
||||
in_memory_llm_clients_cache.set_cache(
|
||||
key="async-redis-client", value=redis_async_client
|
||||
key=cache_key, value=redis_async_client
|
||||
)
|
||||
|
||||
self.redis_async_client = redis_async_client # type: ignore
|
||||
|
|
|
|||
|
|
@ -167,24 +167,27 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
)
|
||||
elif role == "tool":
|
||||
# Convert tool message to function call output format
|
||||
# Transform content to responses format (handles str, list, and other types)
|
||||
# _convert_content_to_responses_format always returns List[Dict[str, Any]]
|
||||
# The Responses API expects 'output' to be a list with input_text/input_image types
|
||||
# Using list format for consistency across text and multimodal content
|
||||
tool_output: List[Dict[str, Any]]
|
||||
if content is None:
|
||||
transformed_output: list[dict[str, Any]] = []
|
||||
elif isinstance(content, (str, list)):
|
||||
transformed_output = self._convert_content_to_responses_format(
|
||||
content, "tool"
|
||||
tool_output = []
|
||||
elif isinstance(content, str):
|
||||
# Convert string to list with input_text
|
||||
tool_output = [{"type": "input_text", "text": content}]
|
||||
elif isinstance(content, list):
|
||||
# Transform list content to Responses API format
|
||||
tool_output = self._convert_content_to_responses_format(
|
||||
content, "user" # Use "user" role to get input_* types
|
||||
)
|
||||
else:
|
||||
# Fallback: convert unexpected types to string first
|
||||
transformed_output = self._convert_content_to_responses_format(
|
||||
str(content), "tool"
|
||||
)
|
||||
# Fallback: convert unexpected types to input_text
|
||||
tool_output = [{"type": "input_text", "text": str(content)}]
|
||||
input_items.append(
|
||||
{
|
||||
"type": "function_call_output",
|
||||
"call_id": tool_call_id,
|
||||
"output": transformed_output,
|
||||
"output": tool_output,
|
||||
}
|
||||
)
|
||||
elif role == "assistant" and tool_calls and isinstance(tool_calls, list):
|
||||
|
|
@ -345,6 +348,11 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
index = 0
|
||||
reasoning_content: Optional[str] = None
|
||||
|
||||
# Collect all tool calls to put them in a single choice
|
||||
# (Chat Completions API expects all tool calls in one message)
|
||||
accumulated_tool_calls: List[Dict[str, Any]] = []
|
||||
tool_call_index = 0
|
||||
|
||||
for item in output_items:
|
||||
if isinstance(item, ResponseReasoningItem):
|
||||
for summary_item in item.summary:
|
||||
|
|
@ -378,20 +386,10 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
|
||||
tool_call_dict = LiteLLMCompletionResponsesConfig.convert_response_function_tool_call_to_chat_completion_tool_call(
|
||||
tool_call_item=item,
|
||||
index=index,
|
||||
index=tool_call_index,
|
||||
)
|
||||
|
||||
msg = Message(
|
||||
content=None,
|
||||
tool_calls=[tool_call_dict],
|
||||
reasoning_content=reasoning_content,
|
||||
)
|
||||
|
||||
choices.append(
|
||||
Choices(message=msg, finish_reason="tool_calls", index=index)
|
||||
)
|
||||
reasoning_content = None # flush reasoning content
|
||||
index += 1
|
||||
accumulated_tool_calls.append(tool_call_dict)
|
||||
tool_call_index += 1
|
||||
|
||||
elif isinstance(item, dict) and handle_raw_dict_callback is not None:
|
||||
# Handle raw dict responses (e.g., from GPT-5 Codex)
|
||||
|
|
@ -401,6 +399,18 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
else:
|
||||
pass # don't fail request if item in list is not supported
|
||||
|
||||
# If we accumulated tool calls, create a single choice with all of them
|
||||
if accumulated_tool_calls:
|
||||
msg = Message(
|
||||
content=None,
|
||||
tool_calls=accumulated_tool_calls,
|
||||
reasoning_content=reasoning_content,
|
||||
)
|
||||
choices.append(
|
||||
Choices(message=msg, finish_reason="tool_calls", index=index)
|
||||
)
|
||||
reasoning_content = None
|
||||
|
||||
return choices
|
||||
|
||||
def transform_response( # noqa: PLR0915
|
||||
|
|
@ -492,7 +502,7 @@ class LiteLLMResponsesTransformationHandler(CompletionTransformationBridge):
|
|||
def _convert_content_str_to_input_text(
|
||||
self, content: str, role: str
|
||||
) -> Dict[str, Any]:
|
||||
if role == "user" or role == "system":
|
||||
if role == "user" or role == "system" or role == "tool":
|
||||
return {"type": "input_text", "text": content}
|
||||
else:
|
||||
return {"type": "output_text", "text": content}
|
||||
|
|
|
|||
|
|
@ -313,6 +313,8 @@ DD_TRACER_STREAMING_CHUNK_YIELD_RESOURCE = os.getenv(
|
|||
"DD_TRACER_STREAMING_CHUNK_YIELD_RESOURCE", "streaming.chunk.yield"
|
||||
)
|
||||
|
||||
EMAIL_BUDGET_ALERT_TTL = int(os.getenv("EMAIL_BUDGET_ALERT_TTL", 24 * 60 * 60)) # 24 hours in seconds
|
||||
EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE = float(os.getenv("EMAIL_BUDGET_ALERT_MAX_SPEND_ALERT_PERCENTAGE", 0.8)) # 80% of max budget
|
||||
############### LLM Provider Constants ###############
|
||||
### ANTHROPIC CONSTANTS ###
|
||||
ANTHROPIC_SKILLS_API_BETA_VERSION = "skills-2025-10-02"
|
||||
|
|
@ -890,6 +892,7 @@ BEDROCK_INVOKE_PROVIDERS_LITERAL = Literal[
|
|||
"qwen2",
|
||||
"twelvelabs",
|
||||
"openai",
|
||||
"stability",
|
||||
]
|
||||
|
||||
BEDROCK_EMBEDDING_PROVIDERS_LITERAL = Literal[
|
||||
|
|
|
|||
|
|
@ -33,6 +33,7 @@ from litellm.main import (
|
|||
base_llm_aiohttp_handler,
|
||||
base_llm_http_handler,
|
||||
bedrock_image_generation,
|
||||
bedrock_image_edit,
|
||||
openai_chat_completions,
|
||||
openai_image_variations,
|
||||
)
|
||||
|
|
@ -670,7 +671,7 @@ def image_variation(
|
|||
|
||||
|
||||
@client
|
||||
def image_edit(
|
||||
def image_edit( # noqa: PLR0915
|
||||
image: Union[FileTypes, List[FileTypes]],
|
||||
prompt: str,
|
||||
model: Optional[str] = None,
|
||||
|
|
@ -695,6 +696,29 @@ def image_edit(
|
|||
"""
|
||||
local_vars = locals()
|
||||
try:
|
||||
openai_params = [
|
||||
"user",
|
||||
"request_timeout",
|
||||
"api_base",
|
||||
"api_version",
|
||||
"api_key",
|
||||
"deployment_id",
|
||||
"organization",
|
||||
"base_url",
|
||||
"default_headers",
|
||||
"timeout",
|
||||
"max_retries",
|
||||
"n",
|
||||
"quality",
|
||||
"size",
|
||||
"style",
|
||||
"async_call",
|
||||
]
|
||||
litellm_params_list = all_litellm_params
|
||||
default_params = openai_params + litellm_params_list
|
||||
non_default_params = {
|
||||
k: v for k, v in kwargs.items() if k not in default_params
|
||||
} # model-specific params - pass them straight to the model/provider
|
||||
litellm_logging_obj: LiteLLMLoggingObj = kwargs.get("litellm_logging_obj") # type: ignore
|
||||
litellm_call_id: Optional[str] = kwargs.get("litellm_call_id", None)
|
||||
_is_async = kwargs.pop("async_call", False) is True
|
||||
|
|
@ -788,13 +812,14 @@ def image_edit(
|
|||
image_edit_optional_params: ImageEditOptionalRequestParams = (
|
||||
_get_ImageEditRequestUtils().get_requested_image_edit_optional_param(local_vars)
|
||||
)
|
||||
|
||||
# Get optional parameters for the responses API
|
||||
image_edit_request_params: Dict = (
|
||||
_get_ImageEditRequestUtils().get_optional_params_image_edit(
|
||||
model=model,
|
||||
image_edit_provider_config=image_edit_provider_config,
|
||||
image_edit_optional_params=image_edit_optional_params,
|
||||
drop_params=kwargs.get("drop_params"),
|
||||
additional_drop_params=kwargs.get("additional_drop_params"),
|
||||
)
|
||||
)
|
||||
|
||||
|
|
@ -810,6 +835,42 @@ def image_edit(
|
|||
custom_llm_provider=custom_llm_provider,
|
||||
)
|
||||
|
||||
# Route bedrock to its specific handler (AWS signing required)
|
||||
if custom_llm_provider == "bedrock":
|
||||
if model is None:
|
||||
raise Exception("Model needs to be set for bedrock")
|
||||
image_edit_request_params.update(non_default_params)
|
||||
return bedrock_image_edit.image_edit( # type: ignore
|
||||
model=model,
|
||||
image=images,
|
||||
prompt=prompt,
|
||||
timeout=timeout,
|
||||
logging_obj=litellm_logging_obj,
|
||||
optional_params=image_edit_request_params,
|
||||
model_response=ImageResponse(),
|
||||
aimage_edit=_is_async,
|
||||
client=kwargs.get("client"),
|
||||
api_base=kwargs.get("api_base"),
|
||||
extra_headers=extra_headers,
|
||||
api_key=kwargs.get("api_key"),
|
||||
)
|
||||
elif custom_llm_provider == "stability":
|
||||
image_edit_request_params.update(non_default_params)
|
||||
return base_llm_http_handler.image_edit_handler(
|
||||
model=model,
|
||||
image=images,
|
||||
prompt=prompt,
|
||||
image_edit_provider_config=image_edit_provider_config,
|
||||
image_edit_optional_request_params=image_edit_request_params,
|
||||
custom_llm_provider=custom_llm_provider,
|
||||
litellm_params=litellm_params,
|
||||
logging_obj=litellm_logging_obj,
|
||||
extra_headers=extra_headers,
|
||||
extra_body=extra_body,
|
||||
timeout=timeout or DEFAULT_REQUEST_TIMEOUT,
|
||||
_is_async=_is_async,
|
||||
client=kwargs.get("client"),
|
||||
)
|
||||
# Call the handler with _is_async flag instead of directly calling the async handler
|
||||
return base_llm_http_handler.image_edit_handler(
|
||||
model=model,
|
||||
|
|
|
|||
|
|
@ -1,5 +1,5 @@
|
|||
from io import BufferedReader, BytesIO
|
||||
from typing import Any, Dict, cast, get_type_hints
|
||||
from typing import Any, Dict, List, Optional, cast, get_type_hints
|
||||
|
||||
import litellm
|
||||
from litellm.litellm_core_utils.token_counter import get_image_type
|
||||
|
|
@ -14,41 +14,53 @@ class ImageEditRequestUtils:
|
|||
model: str,
|
||||
image_edit_provider_config: BaseImageEditConfig,
|
||||
image_edit_optional_params: ImageEditOptionalRequestParams,
|
||||
drop_params: Optional[bool] = None,
|
||||
additional_drop_params: Optional[List[str]] = None,
|
||||
) -> Dict:
|
||||
"""
|
||||
Get optional parameters for the image edit API.
|
||||
|
||||
Args:
|
||||
params: Dictionary of all parameters
|
||||
model: The model name
|
||||
image_edit_provider_config: The provider configuration for image edit API
|
||||
image_edit_optional_params: The optional parameters for the image edit API
|
||||
drop_params: If True, silently drop unsupported parameters instead of raising
|
||||
additional_drop_params: List of additional parameter names to drop
|
||||
|
||||
Returns:
|
||||
A dictionary of supported parameters for the image edit API
|
||||
"""
|
||||
# Remove None values and internal parameters
|
||||
|
||||
# Get supported parameters for the model
|
||||
supported_params = image_edit_provider_config.get_supported_openai_params(model)
|
||||
|
||||
# Check for unsupported parameters
|
||||
should_drop = litellm.drop_params is True or drop_params is True
|
||||
|
||||
filtered_optional_params = dict(image_edit_optional_params)
|
||||
if additional_drop_params:
|
||||
for param in additional_drop_params:
|
||||
filtered_optional_params.pop(param, None)
|
||||
|
||||
unsupported_params = [
|
||||
param
|
||||
for param in image_edit_optional_params
|
||||
for param in filtered_optional_params
|
||||
if param not in supported_params
|
||||
]
|
||||
|
||||
if unsupported_params:
|
||||
raise litellm.UnsupportedParamsError(
|
||||
model=model,
|
||||
message=f"The following parameters are not supported for model {model}: {', '.join(unsupported_params)}",
|
||||
)
|
||||
if should_drop:
|
||||
for param in unsupported_params:
|
||||
filtered_optional_params.pop(param, None)
|
||||
else:
|
||||
raise litellm.UnsupportedParamsError(
|
||||
model=model,
|
||||
message=f"The following parameters are not supported for model {model}: {', '.join(unsupported_params)}",
|
||||
)
|
||||
|
||||
# Map parameters to provider-specific format
|
||||
mapped_params = image_edit_provider_config.map_openai_params(
|
||||
image_edit_optional_params=image_edit_optional_params,
|
||||
image_edit_optional_params=cast(
|
||||
ImageEditOptionalRequestParams, filtered_optional_params
|
||||
),
|
||||
model=model,
|
||||
drop_params=litellm.drop_params,
|
||||
drop_params=should_drop,
|
||||
)
|
||||
|
||||
return mapped_params
|
||||
|
|
@ -70,7 +82,6 @@ class ImageEditRequestUtils:
|
|||
filtered_params = {
|
||||
k: v for k, v in params.items() if k in valid_keys and v is not None
|
||||
}
|
||||
|
||||
return cast(ImageEditOptionalRequestParams, filtered_params)
|
||||
|
||||
@staticmethod
|
||||
|
|
|
|||
|
|
@ -77,8 +77,9 @@ class ProjectedLimitExceededAlert(BaseBudgetAlertType):
|
|||
def get_budget_alert_type(
|
||||
type: Literal[
|
||||
"token_budget",
|
||||
"soft_budget",
|
||||
"user_budget",
|
||||
"soft_budget",
|
||||
"max_budget_alert",
|
||||
"team_budget",
|
||||
"organization_budget",
|
||||
"proxy_budget",
|
||||
|
|
@ -91,6 +92,7 @@ def get_budget_alert_type(
|
|||
"proxy_budget": ProxyBudgetAlert(),
|
||||
"soft_budget": SoftBudgetAlert(),
|
||||
"user_budget": UserBudgetAlert(),
|
||||
"max_budget_alert": TokenBudgetAlert(),
|
||||
"team_budget": TeamBudgetAlert(),
|
||||
"organization_budget": OrganizationBudgetAlert(),
|
||||
"token_budget": TokenBudgetAlert(),
|
||||
|
|
|
|||
|
|
@ -531,8 +531,9 @@ class SlackAlerting(CustomBatchLogger):
|
|||
self,
|
||||
type: Literal[
|
||||
"token_budget",
|
||||
"soft_budget",
|
||||
"user_budget",
|
||||
"soft_budget",
|
||||
"max_budget_alert",
|
||||
"team_budget",
|
||||
"organization_budget",
|
||||
"proxy_budget",
|
||||
|
|
|
|||
|
|
@ -1,12 +1,10 @@
|
|||
import os
|
||||
from typing import TYPE_CHECKING, Any, Optional, Union
|
||||
from datetime import datetime
|
||||
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.integrations.arize import _utils
|
||||
from litellm.integrations.arize._utils import ArizeOTELAttributes
|
||||
from litellm.types.integrations.arize_phoenix import ArizePhoenixConfig
|
||||
from litellm.types.services import ServiceLoggerPayload
|
||||
from litellm.integrations.opentelemetry import OpenTelemetry
|
||||
|
||||
if TYPE_CHECKING:
|
||||
|
|
@ -35,13 +33,19 @@ class ArizePhoenixLogger(OpenTelemetry):
|
|||
@staticmethod
|
||||
def set_arize_phoenix_attributes(span: Span, kwargs, response_obj):
|
||||
_utils.set_attributes(span, kwargs, response_obj, ArizeOTELAttributes)
|
||||
|
||||
# Set project name on the span for all traces to go to custom Phoenix projects
|
||||
config = ArizePhoenixLogger.get_arize_phoenix_config()
|
||||
if config.project_name:
|
||||
from litellm.integrations.opentelemetry_utils.base_otel_llm_obs_attributes import safe_set_attribute
|
||||
safe_set_attribute(span, "openinference.project.name", config.project_name)
|
||||
|
||||
return
|
||||
|
||||
@staticmethod
|
||||
def get_arize_phoenix_config() -> ArizePhoenixConfig:
|
||||
"""
|
||||
Retrieves the Arize Phoenix configuration based on environment variables.
|
||||
|
||||
Returns:
|
||||
ArizePhoenixConfig: A Pydantic model containing Arize Phoenix configuration.
|
||||
"""
|
||||
|
|
@ -95,7 +99,7 @@ class ArizePhoenixLogger(OpenTelemetry):
|
|||
"PHOENIX_API_KEY must be set when using Phoenix Cloud (app.phoenix.arize.com)."
|
||||
)
|
||||
|
||||
project_name = os.environ.get("PHOENIX_PROJECT_NAME", "litellm-project")
|
||||
project_name = os.environ.get("PHOENIX_PROJECT_NAME", "default")
|
||||
|
||||
return ArizePhoenixConfig(
|
||||
otlp_auth_headers=otlp_auth_headers,
|
||||
|
|
@ -103,34 +107,8 @@ class ArizePhoenixLogger(OpenTelemetry):
|
|||
endpoint=endpoint,
|
||||
project_name=project_name,
|
||||
)
|
||||
|
||||
async def async_service_success_hook(
|
||||
self,
|
||||
payload: ServiceLoggerPayload,
|
||||
parent_otel_span: Optional[Span] = None,
|
||||
start_time: Optional[Union[datetime, float]] = None,
|
||||
end_time: Optional[Union[datetime, float]] = None,
|
||||
event_metadata: Optional[dict] = None,
|
||||
):
|
||||
pass # suppress additional spans
|
||||
|
||||
async def async_service_failure_hook(
|
||||
self,
|
||||
payload: ServiceLoggerPayload,
|
||||
error: Optional[str] = "",
|
||||
parent_otel_span: Optional[Span] = None,
|
||||
start_time: Optional[Union[datetime, float]] = None,
|
||||
end_time: Optional[Union[float, datetime]] = None,
|
||||
event_metadata: Optional[dict] = None,
|
||||
):
|
||||
pass # suppress additional spans
|
||||
|
||||
def create_litellm_proxy_request_started_span(
|
||||
self,
|
||||
start_time: datetime,
|
||||
headers: dict,
|
||||
):
|
||||
pass # suppress additional spans
|
||||
|
||||
## cannot suppress additional proxy server spans, removed previous methods.
|
||||
|
||||
async def async_health_check(self):
|
||||
|
||||
|
|
|
|||
4
litellm/integrations/azure_sentinel/__init__.py
Normal file
|
|
@ -0,0 +1,4 @@
|
|||
from litellm.integrations.azure_sentinel.azure_sentinel import AzureSentinelLogger
|
||||
|
||||
__all__ = ["AzureSentinelLogger"]
|
||||
|
||||
304
litellm/integrations/azure_sentinel/azure_sentinel.py
Normal file
|
|
@ -0,0 +1,304 @@
|
|||
"""
|
||||
Azure Sentinel Integration - sends logs to Azure Log Analytics using Logs Ingestion API
|
||||
|
||||
Azure Sentinel uses Log Analytics workspaces for data storage. This integration sends
|
||||
LiteLLM logs to the Log Analytics workspace using the Azure Monitor Logs Ingestion API.
|
||||
|
||||
Reference API: https://learn.microsoft.com/en-us/azure/azure-monitor/logs/logs-ingestion-api-overview
|
||||
|
||||
`async_log_success_event` - used by litellm proxy to send logs to Azure Sentinel
|
||||
`async_log_failure_event` - used by litellm proxy to send failure logs to Azure Sentinel
|
||||
|
||||
For batching specific details see CustomBatchLogger class
|
||||
"""
|
||||
|
||||
import asyncio
|
||||
import os
|
||||
import traceback
|
||||
from typing import List, Optional
|
||||
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.integrations.custom_batch_logger import CustomBatchLogger
|
||||
from litellm.llms.custom_httpx.http_handler import (
|
||||
get_async_httpx_client,
|
||||
httpxSpecialProvider,
|
||||
)
|
||||
from litellm.types.utils import StandardLoggingPayload
|
||||
|
||||
|
||||
class AzureSentinelLogger(CustomBatchLogger):
|
||||
"""
|
||||
Logger that sends LiteLLM logs to Azure Sentinel via Azure Monitor Logs Ingestion API
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
dcr_immutable_id: Optional[str] = None,
|
||||
stream_name: Optional[str] = None,
|
||||
endpoint: Optional[str] = None,
|
||||
tenant_id: Optional[str] = None,
|
||||
client_id: Optional[str] = None,
|
||||
client_secret: Optional[str] = None,
|
||||
**kwargs,
|
||||
):
|
||||
"""
|
||||
Initialize Azure Sentinel logger using Logs Ingestion API
|
||||
|
||||
Args:
|
||||
dcr_immutable_id (str, optional): Data Collection Rule (DCR) Immutable ID.
|
||||
If not provided, will use AZURE_SENTINEL_DCR_IMMUTABLE_ID env var.
|
||||
stream_name (str, optional): Stream name from DCR (e.g., "Custom-LiteLLM").
|
||||
If not provided, will use AZURE_SENTINEL_STREAM_NAME env var or default to "Custom-LiteLLM".
|
||||
endpoint (str, optional): Data Collection Endpoint (DCE) or DCR ingestion endpoint.
|
||||
If not provided, will use AZURE_SENTINEL_ENDPOINT env var.
|
||||
tenant_id (str, optional): Azure Tenant ID for OAuth2 authentication.
|
||||
If not provided, will use AZURE_SENTINEL_TENANT_ID or AZURE_TENANT_ID env var.
|
||||
client_id (str, optional): Azure Client ID (Application ID) for OAuth2 authentication.
|
||||
If not provided, will use AZURE_SENTINEL_CLIENT_ID or AZURE_CLIENT_ID env var.
|
||||
client_secret (str, optional): Azure Client Secret for OAuth2 authentication.
|
||||
If not provided, will use AZURE_SENTINEL_CLIENT_SECRET or AZURE_CLIENT_SECRET env var.
|
||||
"""
|
||||
self.async_httpx_client = get_async_httpx_client(
|
||||
llm_provider=httpxSpecialProvider.LoggingCallback
|
||||
)
|
||||
|
||||
self.dcr_immutable_id = (
|
||||
dcr_immutable_id or os.getenv("AZURE_SENTINEL_DCR_IMMUTABLE_ID")
|
||||
)
|
||||
self.stream_name = stream_name or os.getenv(
|
||||
"AZURE_SENTINEL_STREAM_NAME", "Custom-LiteLLM"
|
||||
)
|
||||
self.endpoint = endpoint or os.getenv("AZURE_SENTINEL_ENDPOINT")
|
||||
self.tenant_id = tenant_id or os.getenv("AZURE_SENTINEL_TENANT_ID") or os.getenv(
|
||||
"AZURE_TENANT_ID"
|
||||
)
|
||||
self.client_id = client_id or os.getenv("AZURE_SENTINEL_CLIENT_ID") or os.getenv(
|
||||
"AZURE_CLIENT_ID"
|
||||
)
|
||||
self.client_secret = (
|
||||
client_secret
|
||||
or os.getenv("AZURE_SENTINEL_CLIENT_SECRET")
|
||||
or os.getenv("AZURE_CLIENT_SECRET")
|
||||
)
|
||||
|
||||
if not self.dcr_immutable_id:
|
||||
raise ValueError(
|
||||
"AZURE_SENTINEL_DCR_IMMUTABLE_ID is required. Set it as an environment variable or pass dcr_immutable_id parameter."
|
||||
)
|
||||
if not self.endpoint:
|
||||
raise ValueError(
|
||||
"AZURE_SENTINEL_ENDPOINT is required. Set it as an environment variable or pass endpoint parameter."
|
||||
)
|
||||
if not self.tenant_id:
|
||||
raise ValueError(
|
||||
"AZURE_SENTINEL_TENANT_ID or AZURE_TENANT_ID is required. Set it as an environment variable or pass tenant_id parameter."
|
||||
)
|
||||
if not self.client_id:
|
||||
raise ValueError(
|
||||
"AZURE_SENTINEL_CLIENT_ID or AZURE_CLIENT_ID is required. Set it as an environment variable or pass client_id parameter."
|
||||
)
|
||||
if not self.client_secret:
|
||||
raise ValueError(
|
||||
"AZURE_SENTINEL_CLIENT_SECRET or AZURE_CLIENT_SECRET is required. Set it as an environment variable or pass client_secret parameter."
|
||||
)
|
||||
|
||||
# Build API endpoint: {Endpoint}/dataCollectionRules/{DCR Immutable ID}/streams/{Stream Name}?api-version=2023-01-01
|
||||
self.api_endpoint = (
|
||||
f"{self.endpoint.rstrip('/')}/dataCollectionRules/{self.dcr_immutable_id}/streams/{self.stream_name}?api-version=2023-01-01"
|
||||
)
|
||||
|
||||
# OAuth2 scope for Azure Monitor
|
||||
self.oauth_scope = "https://monitor.azure.com/.default"
|
||||
self.oauth_token: Optional[str] = None
|
||||
self.oauth_token_expires_at: Optional[float] = None
|
||||
|
||||
self.flush_lock = asyncio.Lock()
|
||||
super().__init__(**kwargs, flush_lock=self.flush_lock)
|
||||
asyncio.create_task(self.periodic_flush())
|
||||
self.log_queue: List[StandardLoggingPayload] = []
|
||||
|
||||
async def _get_oauth_token(self) -> str:
|
||||
"""
|
||||
Get OAuth2 Bearer token for Azure Monitor Logs Ingestion API
|
||||
|
||||
Returns:
|
||||
Bearer token string
|
||||
"""
|
||||
# Check if we have a valid cached token
|
||||
import time
|
||||
|
||||
if (
|
||||
self.oauth_token
|
||||
and self.oauth_token_expires_at
|
||||
and time.time() < self.oauth_token_expires_at - 60
|
||||
): # Refresh 60 seconds before expiry
|
||||
return self.oauth_token
|
||||
|
||||
# Get new token using client credentials flow
|
||||
assert self.tenant_id is not None, "tenant_id is required"
|
||||
assert self.client_id is not None, "client_id is required"
|
||||
assert self.client_secret is not None, "client_secret is required"
|
||||
|
||||
token_url = f"https://login.microsoftonline.com/{self.tenant_id}/oauth2/v2.0/token"
|
||||
|
||||
token_data = {
|
||||
"client_id": self.client_id,
|
||||
"client_secret": self.client_secret,
|
||||
"scope": self.oauth_scope,
|
||||
"grant_type": "client_credentials",
|
||||
}
|
||||
|
||||
response = await self.async_httpx_client.post(
|
||||
url=token_url,
|
||||
data=token_data,
|
||||
headers={"Content-Type": "application/x-www-form-urlencoded"},
|
||||
)
|
||||
|
||||
if response.status_code != 200:
|
||||
raise Exception(
|
||||
f"Failed to get OAuth2 token: {response.status_code} - {response.text}"
|
||||
)
|
||||
|
||||
token_response = response.json()
|
||||
self.oauth_token = token_response.get("access_token")
|
||||
expires_in = token_response.get("expires_in", 3600)
|
||||
|
||||
if not self.oauth_token:
|
||||
raise Exception("OAuth2 token response did not contain access_token")
|
||||
|
||||
# Cache token expiry time
|
||||
import time
|
||||
|
||||
self.oauth_token_expires_at = time.time() + expires_in
|
||||
|
||||
return self.oauth_token
|
||||
|
||||
async def async_log_success_event(
|
||||
self, kwargs, response_obj, start_time, end_time
|
||||
):
|
||||
"""
|
||||
Async Log success events to Azure Sentinel
|
||||
|
||||
- Gets StandardLoggingPayload from kwargs
|
||||
- Adds to batch queue
|
||||
- Flushes based on CustomBatchLogger settings
|
||||
|
||||
Raises:
|
||||
Raises a NON Blocking verbose_logger.exception if an error occurs
|
||||
"""
|
||||
try:
|
||||
verbose_logger.debug(
|
||||
"Azure Sentinel: Logging - Enters logging function for model %s", kwargs
|
||||
)
|
||||
standard_logging_payload = kwargs.get("standard_logging_object", None)
|
||||
|
||||
if standard_logging_payload is None:
|
||||
verbose_logger.warning(
|
||||
"Azure Sentinel: standard_logging_object not found in kwargs"
|
||||
)
|
||||
return
|
||||
|
||||
self.log_queue.append(standard_logging_payload)
|
||||
|
||||
if len(self.log_queue) >= self.batch_size:
|
||||
await self.async_send_batch()
|
||||
|
||||
except Exception as e:
|
||||
verbose_logger.exception(
|
||||
f"Azure Sentinel Layer Error - {str(e)}\n{traceback.format_exc()}"
|
||||
)
|
||||
pass
|
||||
|
||||
async def async_log_failure_event(
|
||||
self, kwargs, response_obj, start_time, end_time
|
||||
):
|
||||
"""
|
||||
Async Log failure events to Azure Sentinel
|
||||
|
||||
- Gets StandardLoggingPayload from kwargs
|
||||
- Adds to batch queue
|
||||
- Flushes based on CustomBatchLogger settings
|
||||
|
||||
Raises:
|
||||
Raises a NON Blocking verbose_logger.exception if an error occurs
|
||||
"""
|
||||
try:
|
||||
verbose_logger.debug(
|
||||
"Azure Sentinel: Logging - Enters failure logging function for model %s",
|
||||
kwargs,
|
||||
)
|
||||
standard_logging_payload = kwargs.get("standard_logging_object", None)
|
||||
|
||||
if standard_logging_payload is None:
|
||||
verbose_logger.warning(
|
||||
"Azure Sentinel: standard_logging_object not found in kwargs"
|
||||
)
|
||||
return
|
||||
|
||||
self.log_queue.append(standard_logging_payload)
|
||||
|
||||
if len(self.log_queue) >= self.batch_size:
|
||||
await self.async_send_batch()
|
||||
|
||||
except Exception as e:
|
||||
verbose_logger.exception(
|
||||
f"Azure Sentinel Layer Error - {str(e)}\n{traceback.format_exc()}"
|
||||
)
|
||||
pass
|
||||
|
||||
async def async_send_batch(self):
|
||||
"""
|
||||
Sends the batch of logs to Azure Monitor Logs Ingestion API
|
||||
|
||||
Raises:
|
||||
Raises a NON Blocking verbose_logger.exception if an error occurs
|
||||
"""
|
||||
try:
|
||||
if not self.log_queue:
|
||||
return
|
||||
|
||||
verbose_logger.debug(
|
||||
"Azure Sentinel - about to flush %s events", len(self.log_queue)
|
||||
)
|
||||
|
||||
from litellm.litellm_core_utils.safe_json_dumps import safe_dumps
|
||||
|
||||
# Get OAuth2 token
|
||||
bearer_token = await self._get_oauth_token()
|
||||
|
||||
# Convert log queue to JSON array format expected by Logs Ingestion API
|
||||
# Each log entry should be a JSON object in the array
|
||||
body = safe_dumps(self.log_queue)
|
||||
|
||||
# Set headers for Logs Ingestion API
|
||||
headers = {
|
||||
"Authorization": f"Bearer {bearer_token}",
|
||||
"Content-Type": "application/json",
|
||||
}
|
||||
|
||||
# Send the request
|
||||
response = await self.async_httpx_client.post(
|
||||
url=self.api_endpoint, data=body.encode("utf-8"), headers=headers
|
||||
)
|
||||
|
||||
if response.status_code not in [200, 204]:
|
||||
verbose_logger.error(
|
||||
"Azure Sentinel API error: status_code=%s, response=%s",
|
||||
response.status_code,
|
||||
response.text,
|
||||
)
|
||||
raise Exception(
|
||||
f"Failed to send logs to Azure Sentinel: {response.status_code} - {response.text}"
|
||||
)
|
||||
|
||||
verbose_logger.debug(
|
||||
"Azure Sentinel: Response from API status_code: %s",
|
||||
response.status_code,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
verbose_logger.exception(
|
||||
f"Azure Sentinel Error sending batch API - {str(e)}\n{traceback.format_exc()}"
|
||||
)
|
||||
finally:
|
||||
self.log_queue.clear()
|
||||
|
|
@ -0,0 +1,179 @@
|
|||
{
|
||||
"id": "chatcmpl-2299b6a2-82a3-465a-b47c-04e685a2227f",
|
||||
"trace_id": "97311c60-9a61-4f48-a814-70139ee57868",
|
||||
"call_type": "acompletion",
|
||||
"cache_hit": null,
|
||||
"stream": true,
|
||||
"status": "success",
|
||||
"custom_llm_provider": "openai",
|
||||
"saved_cache_cost": 0.0,
|
||||
"startTime": 1766000068.28466,
|
||||
"endTime": 1766000070.07935,
|
||||
"completionStartTime": 1766000070.07935,
|
||||
"response_time": 1.79468512535095,
|
||||
"model": "gpt-4o",
|
||||
"metadata": {
|
||||
"user_api_key_hash": null,
|
||||
"user_api_key_alias": null,
|
||||
"user_api_key_team_id": null,
|
||||
"user_api_key_org_id": null,
|
||||
"user_api_key_user_id": null,
|
||||
"user_api_key_team_alias": null,
|
||||
"user_api_key_user_email": null,
|
||||
"spend_logs_metadata": null,
|
||||
"requester_ip_address": null,
|
||||
"requester_metadata": null,
|
||||
"user_api_key_end_user_id": null,
|
||||
"prompt_management_metadata": null,
|
||||
"applied_guardrails": [],
|
||||
"mcp_tool_call_metadata": null,
|
||||
"vector_store_request_metadata": null,
|
||||
"guardrail_information": null
|
||||
},
|
||||
"cache_key": null,
|
||||
"response_cost": 0.00022500000000000002,
|
||||
"total_tokens": 30,
|
||||
"prompt_tokens": 10,
|
||||
"completion_tokens": 20,
|
||||
"request_tags": [],
|
||||
"end_user": "",
|
||||
"api_base": "",
|
||||
"model_group": "",
|
||||
"model_id": "",
|
||||
"requester_ip_address": null,
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "Hello, world!"
|
||||
}
|
||||
],
|
||||
"response": {
|
||||
"id": "chatcmpl-2299b6a2-82a3-465a-b47c-04e685a2227f",
|
||||
"created": 1742855151,
|
||||
"model": "gpt-4o",
|
||||
"object": "chat.completion",
|
||||
"system_fingerprint": null,
|
||||
"choices": [
|
||||
{
|
||||
"finish_reason": "stop",
|
||||
"index": 0,
|
||||
"message": {
|
||||
"content": "hi",
|
||||
"role": "assistant",
|
||||
"tool_calls": null,
|
||||
"function_call": null,
|
||||
"provider_specific_fields": null
|
||||
}
|
||||
}
|
||||
],
|
||||
"usage": {
|
||||
"completion_tokens": 20,
|
||||
"prompt_tokens": 10,
|
||||
"total_tokens": 30,
|
||||
"completion_tokens_details": null,
|
||||
"prompt_tokens_details": null
|
||||
}
|
||||
},
|
||||
"model_parameters": {},
|
||||
"hidden_params": {
|
||||
"model_id": null,
|
||||
"cache_key": null,
|
||||
"api_base": "https://api.openai.com",
|
||||
"response_cost": 0.00022500000000000002,
|
||||
"additional_headers": {},
|
||||
"litellm_overhead_time_ms": null,
|
||||
"batch_models": null,
|
||||
"litellm_model_name": "gpt-4o"
|
||||
},
|
||||
"model_map_information": {
|
||||
"model_map_key": "gpt-4o",
|
||||
"model_map_value": {
|
||||
"key": "gpt-4o",
|
||||
"max_tokens": 16384,
|
||||
"max_input_tokens": 128000,
|
||||
"max_output_tokens": 16384,
|
||||
"input_cost_per_token": 2.5e-06,
|
||||
"cache_creation_input_token_cost": null,
|
||||
"cache_read_input_token_cost": 1.25e-06,
|
||||
"input_cost_per_character": null,
|
||||
"input_cost_per_token_above_128k_tokens": null,
|
||||
"input_cost_per_query": null,
|
||||
"input_cost_per_second": null,
|
||||
"input_cost_per_audio_token": null,
|
||||
"input_cost_per_token_batches": 1.25e-06,
|
||||
"output_cost_per_token_batches": 5e-06,
|
||||
"output_cost_per_token": 1e-05,
|
||||
"output_cost_per_audio_token": null,
|
||||
"output_cost_per_character": null,
|
||||
"output_cost_per_token_above_128k_tokens": null,
|
||||
"output_cost_per_character_above_128k_tokens": null,
|
||||
"output_cost_per_second": null,
|
||||
"output_cost_per_image": null,
|
||||
"output_vector_size": null,
|
||||
"litellm_provider": "openai",
|
||||
"mode": "chat",
|
||||
"supports_system_messages": true,
|
||||
"supports_response_schema": true,
|
||||
"supports_vision": true,
|
||||
"supports_function_calling": true,
|
||||
"supports_tool_choice": true,
|
||||
"supports_assistant_prefill": false,
|
||||
"supports_prompt_caching": true,
|
||||
"supports_audio_input": false,
|
||||
"supports_audio_output": false,
|
||||
"supports_pdf_input": false,
|
||||
"supports_embedding_image_input": false,
|
||||
"supports_native_streaming": null,
|
||||
"supports_web_search": true,
|
||||
"search_context_cost_per_query": {
|
||||
"search_context_size_low": 0.03,
|
||||
"search_context_size_medium": 0.035,
|
||||
"search_context_size_high": 0.05
|
||||
},
|
||||
"tpm": null,
|
||||
"rpm": null,
|
||||
"supported_openai_params": [
|
||||
"frequency_penalty",
|
||||
"logit_bias",
|
||||
"logprobs",
|
||||
"top_logprobs",
|
||||
"max_tokens",
|
||||
"max_completion_tokens",
|
||||
"modalities",
|
||||
"prediction",
|
||||
"n",
|
||||
"presence_penalty",
|
||||
"seed",
|
||||
"stop",
|
||||
"stream",
|
||||
"stream_options",
|
||||
"temperature",
|
||||
"top_p",
|
||||
"tools",
|
||||
"tool_choice",
|
||||
"function_call",
|
||||
"functions",
|
||||
"max_retries",
|
||||
"extra_headers",
|
||||
"parallel_tool_calls",
|
||||
"audio",
|
||||
"response_format",
|
||||
"user"
|
||||
]
|
||||
}
|
||||
},
|
||||
"error_str": null,
|
||||
"error_information": {
|
||||
"error_code": "",
|
||||
"error_class": "",
|
||||
"llm_provider": "",
|
||||
"traceback": "",
|
||||
"error_message": ""
|
||||
},
|
||||
"response_cost_failure_debug_info": null,
|
||||
"guardrail_information": null,
|
||||
"standard_built_in_tools_params": {
|
||||
"web_search_options": null,
|
||||
"file_search": null
|
||||
}
|
||||
}
|
||||
|
|
@ -240,6 +240,28 @@ class CustomGuardrail(CustomLogger):
|
|||
return metadata["disable_global_guardrail"]
|
||||
return False
|
||||
|
||||
def _is_valid_response_type(self, result: Any) -> bool:
|
||||
"""
|
||||
Check if result is a valid LLMResponseTypes instance.
|
||||
|
||||
Safely handles TypedDict types which don't support isinstance checks.
|
||||
For non-LiteLLM responses (like passthrough httpx.Response), returns True
|
||||
to allow them through.
|
||||
"""
|
||||
if result is None:
|
||||
return False
|
||||
|
||||
try:
|
||||
# Try isinstance check on valid types that support it
|
||||
response_types = get_args(LLMResponseTypes)
|
||||
return isinstance(result, response_types)
|
||||
except TypeError as e:
|
||||
# TypedDict types don't support isinstance checks
|
||||
# In this case, we can't validate the type, so we allow it through
|
||||
if "TypedDict" in str(e):
|
||||
return True
|
||||
raise
|
||||
|
||||
def get_guardrail_from_metadata(
|
||||
self, data: dict
|
||||
) -> Union[List[str], List[Dict[str, DynamicGuardrailParams]]]:
|
||||
|
|
@ -342,7 +364,7 @@ class CustomGuardrail(CustomLogger):
|
|||
response=response,
|
||||
)
|
||||
|
||||
if result is None or not isinstance(result, get_args(LLMResponseTypes)):
|
||||
if not self._is_valid_response_type(result):
|
||||
return response
|
||||
|
||||
return result
|
||||
|
|
|
|||
|
|
@ -32,6 +32,8 @@ from litellm.types.utils import (
|
|||
)
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from fastapi import HTTPException
|
||||
|
||||
from litellm.caching.caching import DualCache
|
||||
from opentelemetry.trace import Span as _Span
|
||||
|
||||
|
|
@ -348,7 +350,20 @@ class CustomLogger: # https://docs.litellm.ai/docs/observability/custom_callbac
|
|||
original_exception: Exception,
|
||||
user_api_key_dict: UserAPIKeyAuth,
|
||||
traceback_str: Optional[str] = None,
|
||||
):
|
||||
) -> Optional["HTTPException"]:
|
||||
"""
|
||||
Called after an LLM API call fails. Can return or raise HTTPException to transform error responses.
|
||||
|
||||
Args:
|
||||
- request_data: dict - The request data.
|
||||
- original_exception: Exception - The original exception that occurred.
|
||||
- user_api_key_dict: UserAPIKeyAuth - The user API key dictionary.
|
||||
- traceback_str: Optional[str] - The traceback string.
|
||||
|
||||
Returns:
|
||||
- Optional[HTTPException]: Return an HTTPException to transform the error response sent to the client.
|
||||
Return None to use the original exception.
|
||||
"""
|
||||
pass
|
||||
|
||||
async def async_post_call_success_hook(
|
||||
|
|
|
|||
|
|
@ -27,6 +27,13 @@ import litellm
|
|||
from litellm._logging import verbose_logger
|
||||
from litellm._uuid import uuid
|
||||
from litellm.integrations.custom_batch_logger import CustomBatchLogger
|
||||
from litellm.integrations.datadog.datadog_handler import (
|
||||
get_datadog_hostname,
|
||||
get_datadog_service,
|
||||
get_datadog_source,
|
||||
get_datadog_tags,
|
||||
)
|
||||
from litellm.litellm_core_utils.dd_tracing import tracer
|
||||
from litellm.llms.custom_httpx.http_handler import (
|
||||
_get_httpx_client,
|
||||
get_async_httpx_client,
|
||||
|
|
@ -67,23 +74,23 @@ class DataDogLogger(
|
|||
Optional environment variables (DataDog Agent):
|
||||
`LITELLM_DD_AGENT_HOST` - hostname or IP of DataDog agent, example = `"localhost"`
|
||||
`LITELLM_DD_AGENT_PORT` - port of DataDog agent (default: 10518 for logs)
|
||||
|
||||
|
||||
Note: We use LITELLM_DD_AGENT_HOST instead of DD_AGENT_HOST to avoid conflicts
|
||||
with ddtrace which automatically sets DD_AGENT_HOST for APM tracing.
|
||||
"""
|
||||
try:
|
||||
verbose_logger.debug("Datadog: in init datadog logger")
|
||||
|
||||
|
||||
#########################################################
|
||||
# Handle datadog_params set as litellm.datadog_params
|
||||
#########################################################
|
||||
dict_datadog_params = self._get_datadog_params()
|
||||
kwargs.update(dict_datadog_params)
|
||||
|
||||
|
||||
self.async_client = get_async_httpx_client(
|
||||
llm_provider=httpxSpecialProvider.LoggingCallback
|
||||
)
|
||||
|
||||
|
||||
# Configure DataDog endpoint (Agent or Direct API)
|
||||
# Use LITELLM_DD_AGENT_HOST to avoid conflicts with ddtrace's DD_AGENT_HOST
|
||||
dd_agent_host = os.getenv("LITELLM_DD_AGENT_HOST")
|
||||
|
|
@ -91,7 +98,7 @@ class DataDogLogger(
|
|||
self._configure_dd_agent(dd_agent_host=dd_agent_host)
|
||||
else:
|
||||
self._configure_dd_direct_api()
|
||||
|
||||
|
||||
# Optional override for testing
|
||||
self._apply_dd_base_url_override()
|
||||
self.sync_client = _get_httpx_client()
|
||||
|
|
@ -118,17 +125,21 @@ class DataDogLogger(
|
|||
dict_datadog_params = litellm.datadog_params.model_dump()
|
||||
elif isinstance(litellm.datadog_params, Dict):
|
||||
# only allow params that are of DatadogInitParams
|
||||
dict_datadog_params = DatadogInitParams(**litellm.datadog_params).model_dump()
|
||||
dict_datadog_params = DatadogInitParams(
|
||||
**litellm.datadog_params
|
||||
).model_dump()
|
||||
return dict_datadog_params
|
||||
|
||||
def _configure_dd_agent(self, dd_agent_host: str) -> None:
|
||||
"""
|
||||
Configure DataDog Agent for log forwarding
|
||||
|
||||
|
||||
Args:
|
||||
dd_agent_host: Hostname or IP of DataDog agent
|
||||
"""
|
||||
dd_agent_port = os.getenv("LITELLM_DD_AGENT_PORT", "10518") # default port for logs
|
||||
dd_agent_port = os.getenv(
|
||||
"LITELLM_DD_AGENT_PORT", "10518"
|
||||
) # default port for logs
|
||||
self.intake_url = f"http://{dd_agent_host}:{dd_agent_port}/api/v2/logs"
|
||||
self.DD_API_KEY = os.getenv("DD_API_KEY") # Optional when using agent
|
||||
verbose_logger.debug(f"Datadog: Using DD Agent at {self.intake_url}")
|
||||
|
|
@ -136,7 +147,7 @@ class DataDogLogger(
|
|||
def _configure_dd_direct_api(self) -> None:
|
||||
"""
|
||||
Configure direct DataDog API connection
|
||||
|
||||
|
||||
Raises:
|
||||
Exception: If required environment variables are not set
|
||||
"""
|
||||
|
|
@ -144,11 +155,9 @@ class DataDogLogger(
|
|||
raise Exception("DD_API_KEY is not set, set 'DD_API_KEY=<>")
|
||||
if os.getenv("DD_SITE", None) is None:
|
||||
raise Exception("DD_SITE is not set in .env, set 'DD_SITE=<>")
|
||||
|
||||
|
||||
self.DD_API_KEY = os.getenv("DD_API_KEY")
|
||||
self.intake_url = (
|
||||
f"https://http-intake.logs.{os.getenv('DD_SITE')}/api/v2/logs"
|
||||
)
|
||||
self.intake_url = f"https://http-intake.logs.{os.getenv('DD_SITE')}/api/v2/logs"
|
||||
|
||||
def _apply_dd_base_url_override(self) -> None:
|
||||
"""
|
||||
|
|
@ -270,7 +279,7 @@ class DataDogLogger(
|
|||
# Add API key if available (required for direct API, optional for agent)
|
||||
if self.DD_API_KEY:
|
||||
headers["DD-API-KEY"] = self.DD_API_KEY
|
||||
|
||||
|
||||
response = self.sync_client.post(
|
||||
url=self.intake_url,
|
||||
json=dd_payload, # type: ignore
|
||||
|
|
@ -318,18 +327,18 @@ class DataDogLogger(
|
|||
status: DataDogStatus,
|
||||
) -> DatadogPayload:
|
||||
from litellm.litellm_core_utils.safe_json_dumps import safe_dumps
|
||||
|
||||
json_payload = safe_dumps(standard_logging_object)
|
||||
verbose_logger.debug("Datadog: Logger - Logging payload = %s", json_payload)
|
||||
dd_payload = DatadogPayload(
|
||||
ddsource=self._get_datadog_source(),
|
||||
ddtags=self._get_datadog_tags(
|
||||
standard_logging_object=standard_logging_object
|
||||
),
|
||||
hostname=self._get_datadog_hostname(),
|
||||
ddsource=get_datadog_source(),
|
||||
ddtags=get_datadog_tags(standard_logging_object=standard_logging_object),
|
||||
hostname=get_datadog_hostname(),
|
||||
message=json_payload,
|
||||
service=self._get_datadog_service(),
|
||||
service=get_datadog_service(),
|
||||
status=status,
|
||||
)
|
||||
self._add_trace_context_to_payload(dd_payload=dd_payload)
|
||||
return dd_payload
|
||||
|
||||
def create_datadog_logging_payload(
|
||||
|
|
@ -384,18 +393,19 @@ class DataDogLogger(
|
|||
import gzip
|
||||
|
||||
from litellm.litellm_core_utils.safe_json_dumps import safe_dumps
|
||||
|
||||
compressed_data = gzip.compress(safe_dumps(data).encode("utf-8"))
|
||||
|
||||
|
||||
# Build headers
|
||||
headers = {
|
||||
"Content-Encoding": "gzip",
|
||||
"Content-Type": "application/json",
|
||||
}
|
||||
|
||||
|
||||
# Add API key if available (required for direct API, optional for agent)
|
||||
if self.DD_API_KEY:
|
||||
headers["DD-API-KEY"] = self.DD_API_KEY
|
||||
|
||||
|
||||
response = await self.async_client.post(
|
||||
url=self.intake_url,
|
||||
data=compressed_data, # type: ignore
|
||||
|
|
@ -421,13 +431,14 @@ class DataDogLogger(
|
|||
_payload_dict = payload.model_dump()
|
||||
_payload_dict.update(event_metadata or {})
|
||||
from litellm.litellm_core_utils.safe_json_dumps import safe_dumps
|
||||
|
||||
_dd_message_str = safe_dumps(_payload_dict)
|
||||
_dd_payload = DatadogPayload(
|
||||
ddsource=self._get_datadog_source(),
|
||||
ddtags=self._get_datadog_tags(),
|
||||
hostname=self._get_datadog_hostname(),
|
||||
ddsource=get_datadog_source(),
|
||||
ddtags=get_datadog_tags(),
|
||||
hostname=get_datadog_hostname(),
|
||||
message=_dd_message_str,
|
||||
service=self._get_datadog_service(),
|
||||
service=get_datadog_service(),
|
||||
status=DataDogStatus.WARN,
|
||||
)
|
||||
|
||||
|
|
@ -462,13 +473,14 @@ class DataDogLogger(
|
|||
_payload_dict.update(event_metadata or {})
|
||||
|
||||
from litellm.litellm_core_utils.safe_json_dumps import safe_dumps
|
||||
|
||||
_dd_message_str = safe_dumps(_payload_dict)
|
||||
_dd_payload = DatadogPayload(
|
||||
ddsource=self._get_datadog_source(),
|
||||
ddtags=self._get_datadog_tags(),
|
||||
hostname=self._get_datadog_hostname(),
|
||||
ddsource=get_datadog_source(),
|
||||
ddtags=get_datadog_tags(),
|
||||
hostname=get_datadog_hostname(),
|
||||
message=_dd_message_str,
|
||||
service=self._get_datadog_service(),
|
||||
service=get_datadog_service(),
|
||||
status=DataDogStatus.INFO,
|
||||
)
|
||||
|
||||
|
|
@ -530,7 +542,6 @@ class DataDogLogger(
|
|||
else:
|
||||
clean_metadata[key] = value
|
||||
|
||||
|
||||
# Build the initial payload
|
||||
payload = {
|
||||
"id": id,
|
||||
|
|
@ -550,68 +561,70 @@ class DataDogLogger(
|
|||
}
|
||||
|
||||
from litellm.litellm_core_utils.safe_json_dumps import safe_dumps
|
||||
|
||||
json_payload = safe_dumps(payload)
|
||||
|
||||
verbose_logger.debug("Datadog: Logger - Logging payload = %s", json_payload)
|
||||
|
||||
dd_payload = DatadogPayload(
|
||||
ddsource=self._get_datadog_source(),
|
||||
ddtags=self._get_datadog_tags(),
|
||||
hostname=self._get_datadog_hostname(),
|
||||
ddsource=get_datadog_source(),
|
||||
ddtags=get_datadog_tags(),
|
||||
hostname=get_datadog_hostname(),
|
||||
message=json_payload,
|
||||
service=self._get_datadog_service(),
|
||||
service=get_datadog_service(),
|
||||
status=DataDogStatus.INFO,
|
||||
)
|
||||
return dd_payload
|
||||
|
||||
@staticmethod
|
||||
def _get_datadog_tags(
|
||||
standard_logging_object: Optional[StandardLoggingPayload] = None,
|
||||
) -> str:
|
||||
"""
|
||||
Get the datadog tags for the request
|
||||
def _add_trace_context_to_payload(
|
||||
self,
|
||||
dd_payload: DatadogPayload,
|
||||
) -> None:
|
||||
"""Attach Datadog APM trace context if one is active."""
|
||||
|
||||
DD tags need to be as follows:
|
||||
- tags: ["user_handle:dog@gmail.com", "app_version:1.0.0"]
|
||||
"""
|
||||
base_tags = {
|
||||
"env": os.getenv("DD_ENV", "unknown"),
|
||||
"service": os.getenv("DD_SERVICE", "litellm"),
|
||||
"version": os.getenv("DD_VERSION", "unknown"),
|
||||
"HOSTNAME": DataDogLogger._get_datadog_hostname(),
|
||||
"POD_NAME": os.getenv("POD_NAME", "unknown"),
|
||||
}
|
||||
try:
|
||||
trace_context = self._get_active_trace_context()
|
||||
if trace_context is None:
|
||||
return
|
||||
|
||||
tags = [f"{k}:{v}" for k, v in base_tags.items()]
|
||||
|
||||
if standard_logging_object:
|
||||
_request_tags: List[str] = (
|
||||
standard_logging_object.get("request_tags", []) or []
|
||||
dd_payload["dd.trace_id"] = trace_context["trace_id"]
|
||||
span_id = trace_context.get("span_id")
|
||||
if span_id is not None:
|
||||
dd_payload["dd.span_id"] = span_id
|
||||
except Exception:
|
||||
verbose_logger.exception(
|
||||
"Datadog: Failed to attach trace context to payload"
|
||||
)
|
||||
request_tags = [f"request_tag:{tag}" for tag in _request_tags]
|
||||
tags.extend(request_tags)
|
||||
|
||||
return ",".join(tags)
|
||||
def _get_active_trace_context(self) -> Optional[Dict[str, str]]:
|
||||
try:
|
||||
current_span = None
|
||||
current_span_fn = getattr(tracer, "current_span", None)
|
||||
if callable(current_span_fn):
|
||||
current_span = current_span_fn()
|
||||
|
||||
@staticmethod
|
||||
def _get_datadog_source():
|
||||
return os.getenv("DD_SOURCE", "litellm")
|
||||
if current_span is None:
|
||||
current_root_span_fn = getattr(tracer, "current_root_span", None)
|
||||
if callable(current_root_span_fn):
|
||||
current_span = current_root_span_fn()
|
||||
|
||||
@staticmethod
|
||||
def _get_datadog_service():
|
||||
return os.getenv("DD_SERVICE", "litellm-server")
|
||||
if current_span is None:
|
||||
return None
|
||||
|
||||
@staticmethod
|
||||
def _get_datadog_hostname():
|
||||
return os.getenv("HOSTNAME", "")
|
||||
trace_id = getattr(current_span, "trace_id", None)
|
||||
if trace_id is None:
|
||||
return None
|
||||
|
||||
@staticmethod
|
||||
def _get_datadog_env():
|
||||
return os.getenv("DD_ENV", "unknown")
|
||||
|
||||
@staticmethod
|
||||
def _get_datadog_pod_name():
|
||||
return os.getenv("POD_NAME", "unknown")
|
||||
span_id = getattr(current_span, "span_id", None)
|
||||
trace_context: Dict[str, str] = {"trace_id": str(trace_id)}
|
||||
if span_id is not None:
|
||||
trace_context["span_id"] = str(span_id)
|
||||
return trace_context
|
||||
except Exception:
|
||||
verbose_logger.exception(
|
||||
"Datadog: Failed to retrieve active trace context from tracer"
|
||||
)
|
||||
return None
|
||||
|
||||
async def async_health_check(self) -> IntegrationHealthCheckStatus:
|
||||
"""
|
||||
|
|
@ -651,4 +664,4 @@ class DataDogLogger(
|
|||
start_time_utc: Optional[datetimeObj],
|
||||
end_time_utc: Optional[datetimeObj],
|
||||
) -> Optional[dict]:
|
||||
pass
|
||||
pass
|
||||
|
|
|
|||
50
litellm/integrations/datadog/datadog_handler.py
Normal file
|
|
@ -0,0 +1,50 @@
|
|||
"""Shared helpers for Datadog integrations."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
from typing import List, Optional
|
||||
|
||||
from litellm.types.utils import StandardLoggingPayload
|
||||
|
||||
|
||||
def get_datadog_source() -> str:
|
||||
return os.getenv("DD_SOURCE", "litellm")
|
||||
|
||||
|
||||
def get_datadog_service() -> str:
|
||||
return os.getenv("DD_SERVICE", "litellm-server")
|
||||
|
||||
|
||||
def get_datadog_hostname() -> str:
|
||||
return os.getenv("HOSTNAME", "")
|
||||
|
||||
|
||||
def get_datadog_env() -> str:
|
||||
return os.getenv("DD_ENV", "unknown")
|
||||
|
||||
|
||||
def get_datadog_pod_name() -> str:
|
||||
return os.getenv("POD_NAME", "unknown")
|
||||
|
||||
|
||||
def get_datadog_tags(
|
||||
standard_logging_object: Optional[StandardLoggingPayload] = None,
|
||||
) -> str:
|
||||
"""Build Datadog tags string used by multiple integrations."""
|
||||
|
||||
base_tags = {
|
||||
"env": get_datadog_env(),
|
||||
"service": get_datadog_service(),
|
||||
"version": os.getenv("DD_VERSION", "unknown"),
|
||||
"HOSTNAME": get_datadog_hostname(),
|
||||
"POD_NAME": get_datadog_pod_name(),
|
||||
}
|
||||
|
||||
tags: List[str] = [f"{k}:{v}" for k, v in base_tags.items()]
|
||||
|
||||
if standard_logging_object:
|
||||
request_tags = standard_logging_object.get("request_tags", []) or []
|
||||
tags.extend(f"request_tag:{tag}" for tag in request_tags)
|
||||
|
||||
return ",".join(tags)
|
||||
|
|
@ -18,7 +18,10 @@ import httpx
|
|||
import litellm
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.integrations.custom_batch_logger import CustomBatchLogger
|
||||
from litellm.integrations.datadog.datadog import DataDogLogger
|
||||
from litellm.integrations.datadog.datadog_handler import (
|
||||
get_datadog_service,
|
||||
get_datadog_tags,
|
||||
)
|
||||
from litellm.litellm_core_utils.dd_tracing import tracer
|
||||
from litellm.litellm_core_utils.prompt_templates.common_utils import (
|
||||
handle_any_messages_to_chat_completion_str_messages_conversion,
|
||||
|
|
@ -36,7 +39,7 @@ from litellm.types.utils import (
|
|||
)
|
||||
|
||||
|
||||
class DataDogLLMObsLogger(DataDogLogger, CustomBatchLogger):
|
||||
class DataDogLLMObsLogger(CustomBatchLogger):
|
||||
def __init__(self, **kwargs):
|
||||
try:
|
||||
verbose_logger.debug("DataDogLLMObs: Initializing logger")
|
||||
|
|
@ -142,8 +145,8 @@ class DataDogLLMObsLogger(DataDogLogger, CustomBatchLogger):
|
|||
"data": DDIntakePayload(
|
||||
type="span",
|
||||
attributes=DDSpanAttributes(
|
||||
ml_app=self._get_datadog_service(),
|
||||
tags=[self._get_datadog_tags()],
|
||||
ml_app=get_datadog_service(),
|
||||
tags=[get_datadog_tags()],
|
||||
spans=self.log_queue,
|
||||
),
|
||||
),
|
||||
|
|
@ -243,9 +246,7 @@ class DataDogLLMObsLogger(DataDogLogger, CustomBatchLogger):
|
|||
duration=int((end_time - start_time).total_seconds() * 1e9),
|
||||
metrics=metrics,
|
||||
status="error" if error_info else "ok",
|
||||
tags=[
|
||||
self._get_datadog_tags(standard_logging_object=standard_logging_payload)
|
||||
],
|
||||
tags=[get_datadog_tags(standard_logging_object=standard_logging_payload)],
|
||||
)
|
||||
|
||||
apm_trace_id = self._get_apm_trace_id()
|
||||
|
|
|
|||
|
|
@ -60,3 +60,51 @@ USER_INVITED_EMAIL_TEMPLATE = """
|
|||
Best, <br />
|
||||
The LiteLLM team <br />
|
||||
"""
|
||||
|
||||
SOFT_BUDGET_ALERT_EMAIL_TEMPLATE = """
|
||||
<img src="{email_logo_url}" alt="LiteLLM Logo" width="150" height="50" />
|
||||
|
||||
<p> Hi {recipient_email}, <br/>
|
||||
|
||||
Your LiteLLM API key has crossed its <b>soft budget limit of {soft_budget}</b>. <br /> <br />
|
||||
|
||||
<b>Current Spend:</b> {spend} <br />
|
||||
<b>Soft Budget:</b> {soft_budget} <br />
|
||||
{max_budget_info}
|
||||
|
||||
<p style="color: #dc2626; font-weight: 500;">
|
||||
⚠️ Note: Your API requests will continue to work, but you should monitor your usage closely.
|
||||
If you reach your maximum budget, requests will be rejected.
|
||||
</p>
|
||||
|
||||
You can view your usage and manage your budget in the <a href="{base_url}">LiteLLM Dashboard</a>. <br /> <br />
|
||||
|
||||
If you have any questions, please send an email to {email_support_contact} <br /> <br />
|
||||
|
||||
Best, <br />
|
||||
The LiteLLM team <br />
|
||||
"""
|
||||
|
||||
MAX_BUDGET_ALERT_EMAIL_TEMPLATE = """
|
||||
<img src="{email_logo_url}" alt="LiteLLM Logo" width="150" height="50" />
|
||||
|
||||
<p> Hi {recipient_email}, <br/>
|
||||
|
||||
Your LiteLLM API key has reached <b>{percentage}% of its maximum budget</b>. <br /> <br />
|
||||
|
||||
<b>Current Spend:</b> {spend} <br />
|
||||
<b>Maximum Budget:</b> {max_budget} <br />
|
||||
<b>Alert Threshold:</b> {alert_threshold} ({percentage}%) <br />
|
||||
|
||||
<p style="color: #dc2626; font-weight: 500;">
|
||||
⚠️ Warning: You are approaching your maximum budget limit.
|
||||
Once you reach your maximum budget of {max_budget}, all API requests will be rejected.
|
||||
</p>
|
||||
|
||||
You can view your usage and manage your budget in the <a href="{base_url}">LiteLLM Dashboard</a>. <br /> <br />
|
||||
|
||||
If you have any questions, please send an email to {email_support_contact} <br /> <br />
|
||||
|
||||
Best, <br />
|
||||
The LiteLLM team <br />
|
||||
"""
|
||||
|
|
@ -294,6 +294,11 @@ class LangfusePromptManagement(LangFuseLogger, PromptManagementBase, CustomLogge
|
|||
self.async_log_success_event, kwargs, response_obj, start_time, end_time
|
||||
)
|
||||
|
||||
def log_failure_event(self, kwargs, response_obj, start_time, end_time):
|
||||
return run_async_function(
|
||||
self.async_log_failure_event, kwargs, response_obj, start_time, end_time
|
||||
)
|
||||
|
||||
async def async_log_success_event(self, kwargs, response_obj, start_time, end_time):
|
||||
standard_callback_dynamic_params = kwargs.get(
|
||||
"standard_callback_dynamic_params"
|
||||
|
|
|
|||
|
|
@ -1994,10 +1994,7 @@ class OpenTelemetry(CustomLogger):
|
|||
"""
|
||||
Create a span for the received proxy server request.
|
||||
"""
|
||||
# don't create proxy parent spans for arize phoenix - [TODO]: figure out a better way to handle this
|
||||
if self.callback_name == "arize_phoenix":
|
||||
return None
|
||||
|
||||
|
||||
return self.tracer.start_span(
|
||||
name="Received Proxy Server Request",
|
||||
start_time=self._to_ns(start_time),
|
||||
|
|
|
|||
|
|
@ -815,7 +815,20 @@ class PrometheusLogger(CustomLogger):
|
|||
user_api_key_auth_metadata: Optional[dict] = standard_logging_payload[
|
||||
"metadata"
|
||||
].get("user_api_key_auth_metadata")
|
||||
|
||||
# Include top-level metadata fields (excluding nested dictionaries)
|
||||
# This allows accessing fields like requester_ip_address from top-level metadata
|
||||
top_level_metadata = standard_logging_payload.get("metadata", {})
|
||||
top_level_fields: Dict[str, Any] = {}
|
||||
if isinstance(top_level_metadata, dict):
|
||||
top_level_fields = {
|
||||
k: v
|
||||
for k, v in top_level_metadata.items()
|
||||
if not isinstance(v, dict) # Exclude nested dicts to avoid conflicts
|
||||
}
|
||||
|
||||
combined_metadata: Dict[str, Any] = {
|
||||
**top_level_fields, # Include top-level fields first
|
||||
**(_requester_metadata if _requester_metadata else {}),
|
||||
**(user_api_key_auth_metadata if user_api_key_auth_metadata else {}),
|
||||
}
|
||||
|
|
|
|||
|
|
@ -4,7 +4,6 @@ HTTP Handler for Interactions API requests.
|
|||
This module handles the HTTP communication for the Google Interactions API.
|
||||
"""
|
||||
|
||||
import json
|
||||
from typing import (
|
||||
Any,
|
||||
AsyncIterator,
|
||||
|
|
@ -18,7 +17,6 @@ from typing import (
|
|||
import httpx
|
||||
|
||||
import litellm
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.constants import request_timeout
|
||||
from litellm.interactions.streaming_iterator import (
|
||||
InteractionsAPIStreamingIterator,
|
||||
|
|
|
|||
|
|
@ -8,11 +8,10 @@ from the Google Interactions API, similar to the responses API streaming iterato
|
|||
import asyncio
|
||||
import json
|
||||
from datetime import datetime
|
||||
from typing import Any, Dict, Iterator, Optional
|
||||
from typing import Any, Dict, Optional
|
||||
|
||||
import httpx
|
||||
|
||||
import litellm
|
||||
from litellm._logging import verbose_logger
|
||||
from litellm.constants import STREAM_SSE_DONE_STRING
|
||||
from litellm.litellm_core_utils.asyncify import run_async_function
|
||||
|
|
@ -22,7 +21,6 @@ from litellm.litellm_core_utils.llm_response_utils.get_api_base import get_api_b
|
|||
from litellm.litellm_core_utils.thread_pool_executor import executor
|
||||
from litellm.llms.base_llm.interactions.transformation import BaseInteractionsAPIConfig
|
||||
from litellm.types.interactions import (
|
||||
InteractionsAPIResponse,
|
||||
InteractionsAPIStreamingResponse,
|
||||
)
|
||||
from litellm.utils import CustomStreamWrapper
|
||||
|
|
|
|||