mirror of
https://github.com/agentscope-ai/ReMe.git
synced 2026-09-15 23:31:05 +00:00
Merge remote-tracking branch 'origin/main'
# Conflicts:
#	reme/__init__.py
This commit is contained in:
 方应
commit
5898e9e589
169 changed files with 11184 additions and 2807 deletions
4
.github/workflows/python-publish.yml
vendored
4
.github/workflows/python-publish.yml
vendored
|
|
@ -22,9 +22,9 @@ jobs:
|
|||
runs-on: ubuntu-latest
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v4
|
||||
- uses: actions/checkout@v6
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@v5
|
||||
uses: actions/setup-python@v6
|
||||
with:
|
||||
python-version: '3.10'
|
||||
- name: Install dependencies
|
||||
|
|
|
|||
|
|
@ -50,6 +50,7 @@ repos:
|
|||
--disable=W0511,
|
||||
--disable=W0718,
|
||||
--disable=W0122,
|
||||
--disable=W1203,
|
||||
--disable=C0103,
|
||||
--disable=R0913,
|
||||
--disable=R0917,
|
||||
|
|
|
|||
748
README.md
748
README.md
|
|
@ -11,253 +11,185 @@
|
|||
|
||||
<p align="center">
|
||||
<a href="./LICENSE"><img src="https://img.shields.io/badge/license-Apache--2.0-black" alt="License"></a>
|
||||
<a href="./README_EN.md"><img src="https://img.shields.io/badge/English-Click-yellow" alt="English"></a>
|
||||
<a href="./README.md"><img src="https://img.shields.io/badge/简体中文-点击查看-orange" alt="简体中文"></a>
|
||||
<a href="./README.md"><img src="https://img.shields.io/badge/English-Click-yellow" alt="English"></a>
|
||||
<a href="./README_ZH.md"><img src="https://img.shields.io/badge/简体中文-点击查看-orange" alt="简体中文"></a>
|
||||
<a href="https://github.com/agentscope-ai/ReMe"><img src="https://img.shields.io/github/stars/agentscope-ai/ReMe?style=social" alt="GitHub Stars"></a>
|
||||
<a href="https://deepwiki.com/agentscope-ai/ReMe"><img src="https://img.shields.io/badge/DeepWiki-Ask_Devin-navy.svg" alt="DeepWiki"></a>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<strong>A memory management toolkit for AI agents — Remember Me, Refine Me.</strong><br>
|
||||
</p>
|
||||
|
||||
> For legacy versions, see [0.2.x Documentation](docs/README_0_2_x.md)
|
||||
> For the older version, please refer to the [0.2.x documentation](docs/README_0_2_x.md).
|
||||
|
||||
---
|
||||
|
||||
🧠 ReMe is a **memory management framework** built for **AI agents**, offering both **file-based** and **vector-based**
|
||||
memory systems.
|
||||
🧠 ReMe is a memory management framework designed for **AI agents**, providing both file-based and vector-based memory
|
||||
systems.
|
||||
|
||||
It addresses two core problems of agent memory: **limited context windows** (early information gets truncated or lost
|
||||
during
|
||||
long conversations) and **stateless sessions** (new conversations cannot inherit history and always start from scratch).
|
||||
It tackles two core problems of agent memory: **limited context window** (early information is truncated or lost in long
|
||||
conversations) and **stateless sessions** (new sessions cannot inherit history and always start from scratch).
|
||||
|
||||
ReMe gives agents **real memory** — old conversations are automatically condensed, important information is persisted,
|
||||
and the next conversation can recall it automatically.
|
||||
ReMe gives agents **real memory** — old conversations are automatically compacted, important information is persistently
|
||||
stored, and relevant context is automatically recalled in future interactions.
|
||||
|
||||
<details>
|
||||
<summary><b>What you can do with ReMe</b></summary>
|
||||
|
||||
<br>
|
||||
|
||||
- **Personal assistant**: Provide long-term memory for agents like [CoPaw](https://github.com/agentscope-ai/CoPaw),
|
||||
remembering user preferences and conversation history.
|
||||
- **Coding assistant**: Record code style preferences and project context, maintaining a consistent development
|
||||
experience across sessions.
|
||||
- **Customer service bot**: Track user issue history and preference settings for personalized service.
|
||||
- **Task automation**: Learn success/failure patterns from historical tasks to continuously optimize execution
|
||||
strategies.
|
||||
- **Knowledge Q&A**: Build a searchable knowledge base with semantic search and exact matching support.
|
||||
- **Multi-turn dialogue**: Automatically compress long conversations while retaining key information within limited
|
||||
context windows.
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## 📁 File-Based ReMe
|
||||
## 📁 File-based memory system (ReMeLight)
|
||||
|
||||
> Memory as files, files as memory
|
||||
> Memory as files, files as memory.
|
||||
|
||||
Treat **memory as files** — readable, editable, and portable.
|
||||
Treat **memory as files** — readable, editable, and copyable.
|
||||
[CoPaw](https://github.com/agentscope-ai/CoPaw) integrates long-term memory and context management by inheriting from
|
||||
`ReMeLight`.
|
||||
|
||||
| Traditional Memory Systems | File-Based ReMe |
|
||||
|----------------------------|--------------------|
|
||||
| 🗄️ Database storage | 📝 Markdown files |
|
||||
| 🔒 Opaque | 👀 Read anytime |
|
||||
| ❌ Hard to modify | ✏️ Edit directly |
|
||||
| 🚫 Hard to migrate | 📦 Copy to migrate |
|
||||
| Traditional memory system | File-based ReMe |
|
||||
|---------------------------|----------------------|
|
||||
| 🗄️ Database storage | 📝 Markdown files |
|
||||
| 🔒 Opaque | 👀 Always readable |
|
||||
| ❌ Hard to modify | ✏️ Directly editable |
|
||||
| 🚫 Hard to migrate | 📦 Copy to migrate |
|
||||
|
||||
```
|
||||
.reme/
|
||||
├── MEMORY.md # Long-term memory: user preferences, project config, etc.
|
||||
└── memory/
|
||||
└── YYYY-MM-DD.md # Daily logs: work records for the day, written upon compact
|
||||
working_dir/
|
||||
├── MEMORY.md # Long-term memory: persistent info such as user preferences
|
||||
├── memory/
|
||||
│ └── YYYY-MM-DD.md # Daily journal: automatically written after each conversation
|
||||
└── tool_result/ # Cache for long tool outputs (auto-managed, expired entries auto-cleaned)
|
||||
└── <uuid>.txt
|
||||
```
|
||||
|
||||
### Core Capabilities
|
||||
### Core capabilities
|
||||
|
||||
[ReMe File Based](reme/reme_fb.py) is the core class of the file-based memory system. It acts like an **intelligent
|
||||
secretary**, managing all memory-related operations:
|
||||
[ReMeLight](reme/reme_light.py) is the core class of the file-based memory system. It provides full memory management
|
||||
capabilities for AI agents:
|
||||
|
||||
| Method | Function | Key Components |
|
||||
|-----------------|------------------------------------|---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
|
||||
| `start` | 🚀 Start memory system | [BaseFileStore](reme/core/file_store/base_file_store.py) (local file storage)<br/>[BaseFileWatcher](reme/core/file_watcher/base_file_watcher.py) (file watcher)<br/>[BaseEmbeddingModel](reme/core/embedding/base_embedding_model.py) (embedding cache) |
|
||||
| `close` | 📕 Close and save | Close file store, stop file watcher, save embedding cache |
|
||||
| `context_check` | 📏 Check context limit | [ContextChecker](reme/memory/file_based/fb_context_checker.py) |
|
||||
| `compact` | 📦 Compact history to summary | [Compactor](reme/memory/file_based/fb_compactor.py) |
|
||||
| `summary` | 📝 Write important memory to files | [Summarizer](reme/memory/file_based/fb_summarizer.py) |
|
||||
| `memory_search` | 🔍 Semantic memory search | [MemorySearch](reme/memory/tools/chunk/memory_search.py) |
|
||||
| `memory_get` | 📖 Read specified memory file | [MemoryGet](reme/memory/tools/chunk/memory_get.py) |
|
||||
|
||||
---
|
||||
|
||||
## 🗃️ Vector-Based ReMe
|
||||
|
||||
[ReMe Vector Based](reme/reme.py) is the core class for the vector-based memory system, supporting unified management of
|
||||
three memory types:
|
||||
|
||||
| Memory Type | Purpose | Usage Context |
|
||||
|------------------------------|-----------------------------------------------------|---------------|
|
||||
| **Personal memory** | User preferences, habits | `user_name` |
|
||||
| **Task / procedural memory** | Task execution experience, success/failure patterns | `task_name` |
|
||||
| **Tool memory** | Tool usage experience, parameter tuning | `tool_name` |
|
||||
|
||||
### Core Capabilities
|
||||
|
||||
| Method | Function | Description |
|
||||
|--------------------|---------------------|-----------------------------------------------------------|
|
||||
| `summarize_memory` | 🧠 Summarize memory | Automatically extract and store memory from conversations |
|
||||
| `retrieve_memory` | 🔍 Retrieve memory | Retrieve relevant memory by query |
|
||||
| `add_memory` | ➕ Add memory | Manually add memory to vector store |
|
||||
| `get_memory` | 📖 Get memory | Fetch a single memory by ID |
|
||||
| `update_memory` | ✏️ Update memory | Update content or metadata of existing memory |
|
||||
| `delete_memory` | 🗑️ Delete memory | Delete specified memory |
|
||||
| `list_memory` | 📋 List memory | List memories with filtering and sorting |
|
||||
|
||||
---
|
||||
|
||||
## 💻 ReMeCli: Terminal Assistant with File-Based Memory
|
||||
|
||||
<table border="0" cellspacing="0" cellpadding="0" style="border: none;">
|
||||
<tr style="border: none;">
|
||||
<td width="10%" style="border: none; vertical-align: middle; text-align: center;">
|
||||
<strong>马<br>上<br>有<br>钱</strong>
|
||||
</td>
|
||||
<td width="80%" style="border: none;">
|
||||
<video src="https://github.com/user-attachments/assets/d731ae5c-80eb-498b-a22c-8ab2b9169f87" autoplay muted loop controls></video>
|
||||
</td>
|
||||
<td width="10%" style="border: none; vertical-align: middle; text-align: center;">
|
||||
<strong>马<br>到<br>成<br>功</strong>
|
||||
</td>
|
||||
</tr>
|
||||
<table>
|
||||
<tr><th>Category</th><th>Method</th><th>Function</th><th>Key components</th></tr>
|
||||
<tr><td rowspan="4">Context Management</td><td><code>check_context</code></td><td>📊 Check context size</td><td><a href="reme/memory/file_based/components/context_checker.py">ContextChecker</a> — checks whether context exceeds thresholds and splits messages</td></tr>
|
||||
<tr><td><code>compact_memory</code></td><td>📦 Compact history into summary</td><td><a href="reme/memory/file_based/components/compactor.py">Compactor</a> — ReActAgent that generates structured context summaries</td></tr>
|
||||
<tr><td><code>compact_tool_result</code></td><td>✂️ Compact long tool outputs</td><td><a href="reme/memory/file_based/components/tool_result_compactor.py">ToolResultCompactor</a> — truncates long tool outputs and stores them in <code>tool_result/</code> while keeping file references in messages</td></tr>
|
||||
<tr><td><code>pre_reasoning_hook</code></td><td>🔄 Pre-reasoning hook</td><td><code>compact_tool_result</code> + <code>check_context</code> + <code>compact_memory</code> + <code>summary_memory</code> (async)</td></tr>
|
||||
<tr><td rowspan="2">Long-term Memory</td><td><code>summary_memory</code></td><td>📝 Persist important memory to files</td><td><a href="reme/memory/file_based/components/summarizer.py">Summarizer</a> — ReActAgent + file tools (<code>read</code> / <code>write</code> / <code>edit</code>)</td></tr>
|
||||
<tr><td><code>memory_search</code></td><td>🔍 Semantic memory search</td><td><a href="reme/memory/file_based/tools/memory_search.py">MemorySearch</a> — hybrid retrieval with vectors + BM25</td></tr>
|
||||
<tr><td>-</td><td><code>start</code></td><td>🚀 Start memory system</td><td>Initialize file storage, file watcher, and embedding cache; clean up expired tool result files</td></tr>
|
||||
<tr><td>-</td><td><code>close</code></td><td>📕 Shutdown and cleanup</td><td>Clean up tool result files, stop file watcher, and persist embedding cache</td></tr>
|
||||
</table>
|
||||
|
||||
### When Is Memory Written?
|
||||
|
||||
| Scenario | Written to | Trigger |
|
||||
|---------------------------------------------|------------------------|------------------------------------|
|
||||
| Auto-compact when context is too long | `memory/YYYY-MM-DD.md` | Automatic in background |
|
||||
| User runs `/compact` | `memory/YYYY-MM-DD.md` | Manual compact + background save |
|
||||
| User runs `/new` | `memory/YYYY-MM-DD.md` | New conversation + background save |
|
||||
| User says "remember this" | `MEMORY.md` or log | Agent writes via `write` tool |
|
||||
| Agent finds important decisions/preferences | `MEMORY.md` | Agent writes proactively |
|
||||
|
||||
### Memory Retrieval Tools
|
||||
|
||||
| Method | Tool | When to use | Example |
|
||||
|-----------------|-----------------|----------------------------------|---------------------------------------|
|
||||
| Semantic search | `memory_search` | Unsure where it is, fuzzy lookup | "Earlier discussion about deployment" |
|
||||
| Direct read | `read` | Know the date or file | Read `memory/2025-02-13.md` |
|
||||
|
||||
Search uses **vector + BM25 hybrid retrieval** (vector weight 0.7, BM25 weight 0.3), so queries using both natural
|
||||
language and exact
|
||||
keywords can match.
|
||||
|
||||
### Built-in Tools
|
||||
|
||||
| Tool | Function | Details |
|
||||
|-----------------|----------------|------------------------------------------------------------|
|
||||
| `memory_search` | Search memory | Vector + BM25 hybrid search over MEMORY.md and memory/*.md |
|
||||
| `bash` | Run commands | Execute bash commands with timeout and output truncation |
|
||||
| `ls` | List directory | Show directory structure |
|
||||
| `read` | Read file | Text and images supported, with segmented reading |
|
||||
| `edit` | Edit file | Replace after exact text match |
|
||||
| `write` | Write file | Create or overwrite, auto-create directories |
|
||||
| `execute_code` | Run Python | Execute code snippets |
|
||||
| `web_search` | Web search | Search via Tavily |
|
||||
|
||||
---
|
||||
|
||||
## 🚀 Quick Start
|
||||
### 🚀 Quick start
|
||||
|
||||
### Installation
|
||||
#### Installation
|
||||
|
||||
**Install from source:**
|
||||
|
||||
```bash
|
||||
pip install -U reme-ai
|
||||
git clone https://github.com/agentscope-ai/ReMe.git
|
||||
cd ReMe
|
||||
pip install -e ".[light]"
|
||||
```
|
||||
|
||||
### Environment Variables
|
||||
|
||||
API keys are set via environment variables; you can put them in a `.env` file in the project root:
|
||||
|
||||
| Variable | Description | Example |
|
||||
|---------------------------|----------------------------------|-----------------------------------------------------|
|
||||
| `REME_LLM_API_KEY` | LLM API key | `sk-xxx` |
|
||||
| `REME_LLM_BASE_URL` | LLM base URL | `https://dashscope.aliyuncs.com/compatible-mode/v1` |
|
||||
| `REME_EMBEDDING_API_KEY` | Embedding API key | `sk-xxx` |
|
||||
| `REME_EMBEDDING_BASE_URL` | Embedding base URL | `https://dashscope.aliyuncs.com/compatible-mode/v1` |
|
||||
| `TAVILY_API_KEY` | Tavily search API key (optional) | `tvly-xxx` |
|
||||
|
||||
### Using ReMeCli
|
||||
|
||||
#### Start ReMeCli
|
||||
**Update to the latest version:**
|
||||
|
||||
```bash
|
||||
remecli config=cli
|
||||
git pull
|
||||
pip install -e ".[light]"
|
||||
```
|
||||
|
||||
#### ReMeCli System Commands
|
||||
#### Environment variables
|
||||
|
||||
> Year of the Horse easter egg: `/horse` — fireworks, galloping animation, and random horse-year blessings.
|
||||
`ReMeLight` uses environment variables to configure the embedding model and storage backends:
|
||||
|
||||
Commands starting with `/` control session state:
|
||||
| Variable | Description | Example |
|
||||
|----------------------|-------------------------------|-----------------------------------------------------|
|
||||
| `LLM_API_KEY` | LLM API key | `sk-xxx` |
|
||||
| `LLM_BASE_URL` | LLM base URL | `https://dashscope.aliyuncs.com/compatible-mode/v1` |
|
||||
| `EMBEDDING_API_KEY` | Embedding API key (optional) | `sk-xxx` |
|
||||
| `EMBEDDING_BASE_URL` | Embedding base URL (optional) | `https://dashscope.aliyuncs.com/compatible-mode/v1` |
|
||||
|
||||
| Command | Description | Waits for response |
|
||||
|------------|--------------------------------------------------------------------|--------------------|
|
||||
| `/compact` | Manually compact current conversation and save to long-term memory | Yes |
|
||||
| `/new` | Start new conversation; history saved to long-term memory | No |
|
||||
| `/clear` | Clear everything, **without saving** | No |
|
||||
| `/history` | View uncompressed messages in current conversation | No |
|
||||
| `/help` | Show command list | No |
|
||||
| `/exit` | Exit | No |
|
||||
|
||||
**Difference between the three commands**
|
||||
|
||||
| Command | Compact summary | Long-term memory | Message history |
|
||||
|------------|-----------------|------------------|-----------------|
|
||||
| `/compact` | New summary | Saved | Keep recent |
|
||||
| `/new` | Cleared | Saved | Cleared |
|
||||
| `/clear` | Cleared | Not saved | Cleared |
|
||||
|
||||
> `/clear` permanently deletes; nothing is persisted anywhere.
|
||||
|
||||
### Using the ReMe Package
|
||||
|
||||
#### File-Based ReMe
|
||||
#### Python usage
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
|
||||
from reme import ReMeFb
|
||||
from reme.reme_light import ReMeLight
|
||||
|
||||
|
||||
async def main():
|
||||
# Initialize and start
|
||||
reme = ReMeFb(
|
||||
default_llm_config={
|
||||
"backend": "openai", # Backend type, OpenAI-compatible API
|
||||
"model_name": "qwen3.5-plus", # Model name
|
||||
},
|
||||
default_file_store_config={
|
||||
"backend": "chroma", # Store backend: sqlite/chroma/local
|
||||
"fts_enabled": True, # Enable full-text search
|
||||
"vector_enabled": False, # Enable vector search (set False if no embedding service)
|
||||
},
|
||||
context_window_tokens=128000, # Model context window size (tokens)
|
||||
reserve_tokens=36000, # Tokens reserved for output
|
||||
keep_recent_tokens=20000, # Tokens to keep for recent messages
|
||||
vector_weight=0.7, # Vector search weight (0–1) for hybrid search
|
||||
candidate_multiplier=3.0, # Candidate multiplier for recall
|
||||
# Initialize ReMeLight
|
||||
reme = ReMeLight(
|
||||
default_as_llm_config={"model_name": "qwen3.5-35b-a3b"},
|
||||
# default_embedding_model_config={"model_name": "text-embedding-v4"},
|
||||
default_file_store_config={"fts_enabled": True, "vector_enabled": False},
|
||||
)
|
||||
await reme.start()
|
||||
|
||||
messages = [
|
||||
{"role": "user", "content": "I prefer Python 3.12"},
|
||||
{"role": "assistant", "content": "Noted, you prefer Python 3.12"},
|
||||
]
|
||||
messages = [...] # List of conversation messages
|
||||
|
||||
# Check if context exceeds limit
|
||||
result = await reme.context_check(messages)
|
||||
print(f"Compact result: {result}")
|
||||
# 1. Compact long tool outputs (prevent tool results from blowing up context)
|
||||
messages = await reme.compact_tool_result(messages)
|
||||
|
||||
# Compact conversation to summary
|
||||
summary = await reme.compact(messages_to_summarize=messages)
|
||||
print(f"Summary: {summary}")
|
||||
# 2. Compact conversation history into a structured summary
|
||||
summary = await reme.compact_memory(
|
||||
messages=messages,
|
||||
previous_summary="",
|
||||
max_input_length=128000, # Model context window (tokens)
|
||||
compact_ratio=0.7, # Trigger compaction when exceeding max_input_length * 0.7
|
||||
language="zh", # Summary language (e.g., "zh" / "")
|
||||
)
|
||||
|
||||
# Write important memory to files (ReAct Agent does this automatically)
|
||||
await reme.summary(messages=messages, date="2026-02-28")
|
||||
# 3. Submit summary task asynchronously (non-blocking, writes to memory/YYYY-MM-DD.md)
|
||||
reme.add_async_summary_task(messages=messages)
|
||||
|
||||
# Semantic search over memory
|
||||
results = await reme.memory_search(query="Python version preference", max_results=5)
|
||||
print(f"Search results: {results}")
|
||||
# 4. Pre-reasoning hook (auto compact tool results + generate summaries)
|
||||
processed_messages, compressed_summary = await reme.pre_reasoning_hook(
|
||||
messages=messages,
|
||||
system_prompt="You are a helpful AI assistant.",
|
||||
compressed_summary="",
|
||||
max_input_length=128000,
|
||||
compact_ratio=0.7,
|
||||
memory_compact_reserve=10000,
|
||||
enable_tool_result_compact=True,
|
||||
tool_result_compact_keep_n=3,
|
||||
)
|
||||
|
||||
# Read specified memory file
|
||||
content = await reme.memory_get(path="MEMORY.md")
|
||||
print(f"Memory content: {content}")
|
||||
# 5. Semantic memory search (vector + BM25 hybrid retrieval)
|
||||
result = await reme.memory_search(query="Python version preference", max_results=5)
|
||||
|
||||
# Close (save embedding cache, stop file watcher)
|
||||
# 6. Create in-session memory instance (manages context for one conversation)
|
||||
from reme.memory.file_based.reme_in_memory_memory import ReMeInMemoryMemory
|
||||
memory = ReMeInMemoryMemory()
|
||||
for msg in messages:
|
||||
await memory.add(msg)
|
||||
token_stats = await memory.estimate_tokens(max_input_length=128000)
|
||||
print(f"Current context usage: {token_stats['context_usage_ratio']:.1f}%")
|
||||
print(f"Message token count: {token_stats['messages_tokens']}")
|
||||
print(f"Estimated total tokens: {token_stats['estimated_tokens']}")
|
||||
|
||||
# 7. Wait for background summary tasks to complete before shutdown
|
||||
summary_result = await reme.await_summary_tasks()
|
||||
|
||||
# Shutdown ReMeLight
|
||||
await reme.close()
|
||||
|
||||
|
||||
|
|
@ -265,10 +197,230 @@ if __name__ == "__main__":
|
|||
asyncio.run(main())
|
||||
```
|
||||
|
||||
#### Vector-Based ReMe
|
||||
> 📂 Full example: [test_reme_light.py](tests/light/test_reme_light.py)
|
||||
> 📋 Sample run log: [test_reme_light_log.txt](tests/light/test_reme_light_log.txt) (223,838 tokens → 1,105 tokens, 99.5%
|
||||
> compression)
|
||||
|
||||
### Architecture of the file-based ReMeLight memory system
|
||||
|
||||
[CoPaw MemoryManager](https://github.com/agentscope-ai/CoPaw/blob/main/src/copaw/agents/memory/memory_manager.py)
|
||||
inherits
|
||||
`ReMeLight` and integrates its memory capabilities into the agent reasoning loop:
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
Agent[Agent] -->|Before each reasoning step| Hook[pre_reasoning_hook]
|
||||
Hook --> TC[compact_tool_result<br>Compact tool outputs]
|
||||
TC --> CC[check_context<br>Token counting]
|
||||
CC -->|Exceeds limit| CM[compact_memory<br>Generate summary]
|
||||
CC -->|Exceeds limit| SM[summary_memory<br>Async persistence]
|
||||
SM -->|ReAct + FileIO| Files[memory/*.md]
|
||||
Agent -->|Explicit call| Search[memory_search<br>Vector+BM25]
|
||||
Agent -->|In - session| InMem[ReMeInMemoryMemory<br>Token-aware memory]
|
||||
Files -.->|FileWatcher| Store[(FileStore<br>Vector+FTS index)]
|
||||
Search --> Store
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
#### 1. `check_context` — context checking
|
||||
|
||||
[ContextChecker](reme/memory/file_based/components/context_checker.py) uses token counting to determine whether the
|
||||
context exceeds thresholds and automatically splits messages into a "to compact" group and a "to keep" group.
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
M[messages] --> H[AsMsgHandler<br>Token counting]
|
||||
H --> C{total > threshold?}
|
||||
C -->|No| K[Return all messages]
|
||||
C -->|Yes| S[Keep from tail<br>reserve tokens]
|
||||
S --> CP[messages_to_compact<br>Earlier messages]
|
||||
S --> KP[messages_to_keep<br>Recent messages]
|
||||
S --> V{is_valid<br>Tool calls aligned?}
|
||||
```
|
||||
|
||||
- **Core logic**: keep `reserve` tokens from the tail; mark the rest as messages to compact.
|
||||
- **Integrity guarantee**: preserves complete user-assistant turns and tool_use/tool_result pairs without splitting
|
||||
them.
|
||||
|
||||
---
|
||||
|
||||
#### 2. `compact_memory` — conversation compaction
|
||||
|
||||
[Compactor](reme/memory/file_based/components/compactor.py) uses a ReActAgent to compact conversation history into a *
|
||||
*structured context summary**.
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
M[messages] --> H[AsMsgHandler<br>format_msgs_to_str]
|
||||
H --> A[ReActAgent<br>reme_compactor]
|
||||
P[previous_summary] -->|Incremental update| A
|
||||
A --> S[Structured summary<br>Goal/Progress/Decisions...]
|
||||
```
|
||||
|
||||
**Summary structure** (context checkpoints):
|
||||
|
||||
| Field | Description |
|
||||
|-----------------------|------------------------------------------------------------------------|
|
||||
| `## Goal` | User goals |
|
||||
| `## Constraints` | Constraints and preferences |
|
||||
| `## Progress` | Task progress |
|
||||
| `## Key Decisions` | Key decisions |
|
||||
| `## Next Steps` | Next step plans |
|
||||
| `## Critical Context` | Critical data such as file paths, function names, error messages, etc. |
|
||||
|
||||
- **Incremental updates**: when `previous_summary` is provided, new conversations are merged into the existing summary.
|
||||
|
||||
---
|
||||
|
||||
#### 3. `summary_memory` — persistent memory
|
||||
|
||||
[Summarizer](reme/memory/file_based/components/summarizer.py) uses a **ReAct + file tools** pattern so that the AI can
|
||||
decide what to write and where to write it.
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
M[messages] --> A[ReActAgent<br>reme_summarizer]
|
||||
A -->|read| R[Read memory/YYYY-MM-DD.md]
|
||||
R --> T{Reason: how to merge?}
|
||||
T -->|write| W[Overwrite]
|
||||
T -->|edit| E[Edit in place]
|
||||
W --> F[memory/YYYY-MM-DD.md]
|
||||
E --> F
|
||||
```
|
||||
|
||||
**File tools** ([FileIO](reme/memory/file_based/tools/file_io.py)):
|
||||
|
||||
| Tool | Function |
|
||||
|---------|-----------------------|
|
||||
| `read` | Read file content |
|
||||
| `write` | Overwrite file |
|
||||
| `edit` | Find-and-replace edit |
|
||||
|
||||
---
|
||||
|
||||
#### 4. `compact_tool_result` — tool result compaction
|
||||
|
||||
[ToolResultCompactor](reme/memory/file_based/components/tool_result_compactor.py) addresses the problem of long tool
|
||||
outputs bloating the context.
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
M[messages] --> L{Iterate tool_result<br>len > threshold?}
|
||||
L -->|No| K[Keep as-is]
|
||||
L -->|Yes| T[truncate_text<br>Truncate to threshold]
|
||||
T --> S[Write full content<br>tool_result/uuid.txt]
|
||||
S --> R[Append file path reference<br>to message]
|
||||
R --> C[cleanup_expired_files<br>Delete expired files]
|
||||
```
|
||||
|
||||
- **Auto cleanup**: expired files (older than `retention_days`) are deleted automatically during `start` / `close` /
|
||||
`compact_tool_result`.
|
||||
|
||||
---
|
||||
|
||||
#### 5. `memory_search` — memory retrieval
|
||||
|
||||
[MemorySearch](reme/memory/file_based/tools/memory_search.py) provides **vector + BM25 hybrid retrieval**.
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
Q[query] --> E[Embedding<br>Vectorization]
|
||||
E --> V[vector_search<br>Semantic similarity]
|
||||
Q --> B[BM25<br>Keyword matching]
|
||||
V -->|" weight: 0.7 "| M[Deduplicate + weighted merge]
|
||||
B -->|" weight: 0.3 "| M
|
||||
M --> F[min_score filter]
|
||||
F --> R[Top-N results]
|
||||
```
|
||||
|
||||
- **Fusion mechanism**: vector weight 0.7 + BM25 weight 0.3 — balancing semantic similarity and exact matches.
|
||||
|
||||
---
|
||||
|
||||
#### 6. `ReMeInMemoryMemory` — in-session memory
|
||||
|
||||
[ReMeInMemoryMemory](reme/memory/file_based/reme_in_memory_memory.py) extends AgentScope's `InMemoryMemory` to provide
|
||||
token-aware memory management.
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
C[content] --> G[get_memory<br>exclude_mark=COMPRESSED]
|
||||
G --> F[Filter out compressed messages]
|
||||
F --> P{prepend_summary?}
|
||||
P -->|Yes| S[Prepend previous summary]
|
||||
S --> O[Output messages]
|
||||
P -->|No| O
|
||||
```
|
||||
|
||||
| Function | Description |
|
||||
|----------------------------------|---------------------------------------------------|
|
||||
| `get_memory` | Filter messages by mark and auto-append summary |
|
||||
| `estimate_tokens` | Estimate token usage of the context |
|
||||
| `state_dict` / `load_state_dict` | Serialize/deserialize state (session persistence) |
|
||||
|
||||
---
|
||||
|
||||
#### 7. `pre_reasoning_hook` — pre-reasoning processing
|
||||
|
||||
This is a unified entry point that wires all the above components together and automatically manages context before each
|
||||
reasoning step.
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
M[messages] --> TC[compact_tool_result<br>Compact long tool outputs]
|
||||
TC --> CC[check_context<br>Compute remaining space]
|
||||
CC --> D{messages_to_compact<br>Non-empty?}
|
||||
D -->|No| K[Return original messages + summary]
|
||||
D -->|Yes| V{is_valid?}
|
||||
V -->|No| K
|
||||
V -->|Yes| CM[compact_memory<br>Sync summary generation]
|
||||
V -->|Yes| SM[add_async_summary_task<br>Async persistence]
|
||||
CM --> R[Return messages_to_keep + new summary]
|
||||
```
|
||||
|
||||
**Execution flow**:
|
||||
|
||||
1. `compact_tool_result` — compact long tool outputs.
|
||||
2. `check_context` — check whether the context exceeds limits.
|
||||
3. `compact_memory` — generate compact summary (sync).
|
||||
4. `summary_memory` — persist memory (async in the background).
|
||||
|
||||
---
|
||||
|
||||
## 🗃️ Vector-based memory system
|
||||
|
||||
[ReMe Vector Based](reme/reme.py) is the core class for the vector-based memory system. It manages three types of
|
||||
memories:
|
||||
|
||||
| Memory type | Use case |
|
||||
|-----------------------|-------------------------------------------------------------------|
|
||||
| **Personal memory** | Records user preferences and habits |
|
||||
| **Procedural memory** | Records task execution experience and patterns of success/failure |
|
||||
| **Tool memory** | Records tool usage experience and parameter tuning |
|
||||
|
||||
### Core capabilities
|
||||
|
||||
| Method | Function | Description |
|
||||
|--------------------|--------------|-------------------------------------------------------------|
|
||||
| `summarize_memory` | 🧠 Summarize | Automatically extract and store memories from conversations |
|
||||
| `retrieve_memory` | 🔍 Retrieve | Retrieve related memories based on a query |
|
||||
| `add_memory` | ➕ Add | Manually add memories into the vector store |
|
||||
| `get_memory` | 📖 Get | Get a single memory by ID |
|
||||
| `update_memory` | ✏️ Update | Update existing memory content or metadata |
|
||||
| `delete_memory` | 🗑️ Delete | Delete a specific memory |
|
||||
| `list_memory` | 📋 List | List memories with filtering and sorting |
|
||||
|
||||
### Installation and environment variables
|
||||
|
||||
Installation and environment configuration are the same as [ReMeLight](#installation).
|
||||
API keys are configured via environment variables and can be stored in a `.env` file at the project root.
|
||||
|
||||
### Python usage
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
|
||||
from reme import ReMe
|
||||
|
||||
|
||||
|
|
@ -278,7 +430,7 @@ async def main():
|
|||
working_dir=".reme",
|
||||
default_llm_config={
|
||||
"backend": "openai",
|
||||
"model_name": "qwen3-30b-a3b-thinking-2507",
|
||||
"model_name": "qwen3.5-plus",
|
||||
},
|
||||
default_embedding_model_config={
|
||||
"backend": "openai",
|
||||
|
|
@ -293,33 +445,34 @@ async def main():
|
|||
|
||||
messages = [
|
||||
{"role": "user", "content": "Help me write a Python script", "time_created": "2026-02-28 10:00:00"},
|
||||
{"role": "assistant", "content": "Sure, I'll help you write it", "time_created": "2026-02-28 10:00:05"},
|
||||
{"role": "assistant", "content": "Sure, I'll help you with that.", "time_created": "2026-02-28 10:00:05"},
|
||||
]
|
||||
|
||||
# 1. Summarize memory from conversation (auto-extract user preferences, task experience, etc.)
|
||||
# 1. Summarize memories from conversation (automatically extract user preferences, task experience, etc.)
|
||||
result = await reme.summarize_memory(
|
||||
messages=messages,
|
||||
user_name="alice", # Personal memory
|
||||
# task_name="code_writing", # Task memory
|
||||
# task_name="code_writing", # Procedural memory
|
||||
)
|
||||
print(f"Summarize result: {result}")
|
||||
print(f"Summary result: {result}")
|
||||
|
||||
# 2. Retrieve relevant memory
|
||||
# 2. Retrieve related memories
|
||||
memories = await reme.retrieve_memory(
|
||||
query="Python programming",
|
||||
# user_name="alice",
|
||||
user_name="alice",
|
||||
# task_name="code_writing",
|
||||
)
|
||||
print(f"Retrieve result: {memories}")
|
||||
print(f"Retrieved memories: {memories}")
|
||||
|
||||
# 3. Manually add memory
|
||||
# 3. Manually add a memory
|
||||
memory_node = await reme.add_memory(
|
||||
memory_content="User prefers concise code style",
|
||||
memory_content="The user prefers concise code style.",
|
||||
user_name="alice",
|
||||
)
|
||||
print(f"Added memory: {memory_node}")
|
||||
memory_id = memory_node.memory_id
|
||||
|
||||
# 4. Get single memory by ID
|
||||
# 4. Get a single memory by ID
|
||||
fetched_memory = await reme.get_memory(memory_id=memory_id)
|
||||
print(f"Fetched memory: {fetched_memory}")
|
||||
|
||||
|
|
@ -327,11 +480,11 @@ async def main():
|
|||
updated_memory = await reme.update_memory(
|
||||
memory_id=memory_id,
|
||||
user_name="alice",
|
||||
memory_content="User prefers concise, well-commented code style",
|
||||
memory_content="The user prefers concise code with comments.",
|
||||
)
|
||||
print(f"Updated memory: {updated_memory}")
|
||||
|
||||
# 6. List all memories for user (with filtering and sorting)
|
||||
# 6. List all memories for the user (supports filtering and sorting)
|
||||
all_memories = await reme.list_memory(
|
||||
user_name="alice",
|
||||
limit=10,
|
||||
|
|
@ -340,11 +493,11 @@ async def main():
|
|||
)
|
||||
print(f"User memory list: {all_memories}")
|
||||
|
||||
# 7. Delete specified memory
|
||||
# 7. Delete a specific memory
|
||||
await reme.delete_memory(memory_id=memory_id)
|
||||
print(f"Deleted memory: {memory_id}")
|
||||
|
||||
# 8. Delete all memories (use with caution)
|
||||
# 8. Delete all memories (use with care)
|
||||
# await reme.delete_all()
|
||||
|
||||
await reme.close()
|
||||
|
|
@ -354,118 +507,21 @@ if __name__ == "__main__":
|
|||
asyncio.run(main())
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## 🏛️ Technical Architecture
|
||||
|
||||
### File-Based ReMe Core Architecture
|
||||
|
||||
```mermaid
|
||||
graph TB
|
||||
User[User / Agent] --> ReMeFb[File based ReMe]
|
||||
ReMeFb --> ContextCheck[Context Check]
|
||||
ReMeFb --> Compact[Context Compact]
|
||||
ReMeFb --> Summary[Memory Summary]
|
||||
ReMeFb --> Search[Memory Retrieval]
|
||||
ContextCheck --> FbContextChecker[Check Token Limit]
|
||||
Compact --> FbCompactor[Compact History to Summary]
|
||||
Summary --> FbSummarizer[ReAct Agent + File Tools]
|
||||
Search --> MemorySearch[Vector + BM25 Hybrid Search]
|
||||
FbSummarizer --> FileTools[read / write / edit]
|
||||
FileTools --> MemoryFiles[memory/*.md]
|
||||
MemoryFiles -.->|File change| FileWatcher[Async File Watcher]
|
||||
FileWatcher -->|Update index| FileStore[Local DB]
|
||||
MemorySearch --> FileStore
|
||||
```
|
||||
|
||||
#### Memory Summary: ReAct + File Tools
|
||||
|
||||
[Summarizer](reme/memory/file_based/fb_summarizer.py) is the core component for memory summarization. It uses the
|
||||
**ReAct + file tools** pattern.
|
||||
### Technical architecture
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
A[Receive conversation] --> B{Think: What's worth recording?}
|
||||
B --> C[Act: read memory/YYYY-MM-DD.md]
|
||||
C --> D{Think: How to merge with existing content?}
|
||||
D --> E[Act: edit to update file]
|
||||
E --> F{Think: Anything missing?}
|
||||
F -->|Yes| B
|
||||
F -->|No| G[Done]
|
||||
```
|
||||
|
||||
#### File Tool Set
|
||||
|
||||
Summarizer is equipped with file operation tools so the AI can work directly on memory files:
|
||||
|
||||
| Tool | Function | Use case |
|
||||
|---------|-------------------|-----------------------------------------|
|
||||
| `read` | Read file content | View existing memory, avoid duplicates |
|
||||
| `write` | Overwrite file | Create new memory file or major rewrite |
|
||||
| `edit` | Edit part of file | Append or modify specific sections |
|
||||
|
||||
#### Context Compaction
|
||||
|
||||
When a conversation gets too long, [Compactor](reme/memory/file_based/fb_compactor.py) compresses history into a concise
|
||||
summary — like **meeting minutes**, turning long discussion into key points.
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
A[Messages 1..N] --> B[📦 Compact summary]
|
||||
C[Recent messages] --> D[Keep as-is]
|
||||
B --> E[New context]
|
||||
D --> E
|
||||
```
|
||||
|
||||
The compact summary includes what’s needed to continue:
|
||||
|
||||
| Content | Description |
|
||||
|----------------|---------------------------------------------|
|
||||
| 🎯 Goals | What the user wants to accomplish |
|
||||
| ⚙️ Constraints | Requirements and preferences mentioned |
|
||||
| 📈 Progress | Completed / in progress / blocked tasks |
|
||||
| 🔑 Decisions | Decisions made and reasons |
|
||||
| 📌 Context | Key data such as file paths, function names |
|
||||
|
||||
#### Memory Retrieval
|
||||
|
||||
[MemorySearch](reme/memory/tools/chunk/memory_search.py) provides **vector + BM25 hybrid retrieval**. The two methods
|
||||
complement each other:
|
||||
|
||||
| Retrieval | Strength | Weakness |
|
||||
|---------------------|-------------------------------------------------|----------------------------------------|
|
||||
| **Vector semantic** | Captures similar meaning with different wording | Weaker on exact token match |
|
||||
| **BM25 full-text** | Strong exact token match | No synonym or paraphrase understanding |
|
||||
|
||||
**Fusion**: Both retrieval paths are used; results are combined by weighted sum (vector 0.7 + BM25 0.3), so both
|
||||
natural-language queries and exact lookups get reliable results.
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
Q[Search query] --> V[Vector search × 0.7]
|
||||
Q --> B[BM25 × 0.3]
|
||||
V --> M[Dedupe + weighted merge]
|
||||
B --> M
|
||||
M --> R[Top-N results]
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
### Vector-Based ReMe Core Architecture
|
||||
|
||||
```mermaid
|
||||
graph TB
|
||||
User[User / Agent] --> ReMe[Vector Based ReMe]
|
||||
ReMe --> Summarize[Memory Summarize]
|
||||
ReMe --> Retrieve[Memory Retrieve]
|
||||
ReMe --> CRUD[CRUD]
|
||||
ReMe --> Summarize[Summarize memories]
|
||||
ReMe --> Retrieve[Retrieve memories]
|
||||
ReMe --> CRUD[CRUD operations]
|
||||
Summarize --> PersonalSum[PersonalSummarizer]
|
||||
Summarize --> ProceduralSum[ProceduralSummarizer]
|
||||
Summarize --> ToolSum[ToolSummarizer]
|
||||
Retrieve --> PersonalRet[PersonalRetriever]
|
||||
Retrieve --> ProceduralRet[ProceduralRetriever]
|
||||
Retrieve --> ToolRet[ToolRetriever]
|
||||
PersonalSum --> VectorStore[Vector DB]
|
||||
PersonalSum --> VectorStore[Vector database]
|
||||
ProceduralSum --> VectorStore
|
||||
ToolSum --> VectorStore
|
||||
PersonalRet --> VectorStore
|
||||
|
|
@ -473,19 +529,60 @@ graph TB
|
|||
ToolRet --> VectorStore
|
||||
```
|
||||
|
||||
### Experimental results
|
||||
|
||||
Coming soon...
|
||||
|
||||
---
|
||||
|
||||
## ⭐ Community & Support
|
||||
## 🧪 Procedural memory paper
|
||||
|
||||
- **Star & Watch**: Star helps more agent developers discover ReMe; Watch keeps you updated on new releases and
|
||||
features.
|
||||
- **Share your work**: In Issues or Discussions, share what ReMe unlocks for your agents — we’re happy to highlight
|
||||
great community examples.
|
||||
- **Need a new feature?** Open a Feature Request; we’ll iterate with the community.
|
||||
- **Code contributions**: All forms of code contribution are welcome. See
|
||||
the [Contribution Guide](docs/contribution.md).
|
||||
- **Acknowledgments**: Thanks to OpenClaw, Mem0, MemU, CoPaw, and other open-source projects for inspiration and
|
||||
support.
|
||||
> Our procedural (task) memory paper is available on [arXiv](https://arxiv.org/abs/2512.10696).
|
||||
|
||||
### 🌍 [Appworld benchmark](benchmark/appworld/quickstart.md)
|
||||
|
||||
We evaluate ReMe on the Appworld environment using Qwen3-8B (non-thinking mode):
|
||||
|
||||
| Method | Avg@4 | Pass@4 |
|
||||
|----------|---------------------|---------------------|
|
||||
| w/o ReMe | 0.1497 | 0.3285 |
|
||||
| w/ ReMe | 0.1706 **(+2.09%)** | 0.3631 **(+3.46%)** |
|
||||
|
||||
Pass@K measures the probability that at least one of K generated candidates successfully completes the task (score=1).
|
||||
The current experiments use an internal AppWorld environment, which may differ slightly from the public version.
|
||||
|
||||
For more details on how to reproduce the experiments, see [quickstart.md](benchmark/appworld/quickstart.md).
|
||||
|
||||
### 🔧 [BFCL-V3 benchmark](benchmark/bfcl/quickstart.md)
|
||||
|
||||
We evaluate ReMe on the BFCL-V3 multi-turn-base task (random split 50 train / 150 val) using Qwen3-8B (thinking mode):
|
||||
|
||||
| Method | Avg@4 | Pass@4 |
|
||||
|----------|---------------------|---------------------|
|
||||
| w/o ReMe | 0.4033 | 0.5955 |
|
||||
| w/ ReMe | 0.4450 **(+4.17%)** | 0.6577 **(+6.22%)** |
|
||||
|
||||
For more details on how to reproduce the experiments, see [quickstart.md](benchmark/bfcl/quickstart.md).
|
||||
|
||||
## ⭐ Community & support
|
||||
|
||||
- **Star & Watch**: Starring helps more agent developers discover ReMe; Watching keeps you up to date with new releases
|
||||
and features.
|
||||
- **Share your results**: Share how ReMe empowers your agents in Issues or Discussions — we are happy to showcase great
|
||||
community use cases.
|
||||
- **Need a new feature?** Open a feature request; we’ll evolve ReMe together with the community.
|
||||
- **Code contributions**: All forms of contributions are welcome. Please see
|
||||
the [contribution guide](docs/contribution.md).
|
||||
- **Acknowledgements**: We thank excellent open-source projects such as OpenClaw, Mem0, MemU, and CoPaw for their
|
||||
inspiration and support.
|
||||
|
||||
### Contributors
|
||||
|
||||
Thanks to all who have contributed to ReMe:
|
||||
|
||||
<a href="https://github.com/agentscope-ai/ReMe/graphs/contributors">
|
||||
<img src="https://contrib.rocks/image?repo=agentscope-ai/ReMe" alt="Contributors" />
|
||||
</a>
|
||||
|
||||
---
|
||||
|
||||
|
|
@ -504,10 +601,19 @@ graph TB
|
|||
|
||||
## ⚖️ License
|
||||
|
||||
This project is open source under the Apache License 2.0. See the [LICENSE](./LICENSE) file for details.
|
||||
This project is open-sourced under the Apache License 2.0. See [LICENSE](./LICENSE) for details.
|
||||
|
||||
---
|
||||
|
||||
## 📈 Star History
|
||||
## 🤔 Why ReMe?
|
||||
|
||||
ReMe stands for **Remember Me** and **Refine Me**, symbolizing our goal to help AI agents "remember" users and "refine"
|
||||
themselves through interactions. We hope ReMe is not just a cold memory module, but a partner that truly helps agents
|
||||
understand users, accumulate experience, and continuously evolve.
|
||||
|
||||
---
|
||||
|
||||
## 📈 Star history
|
||||
|
||||
[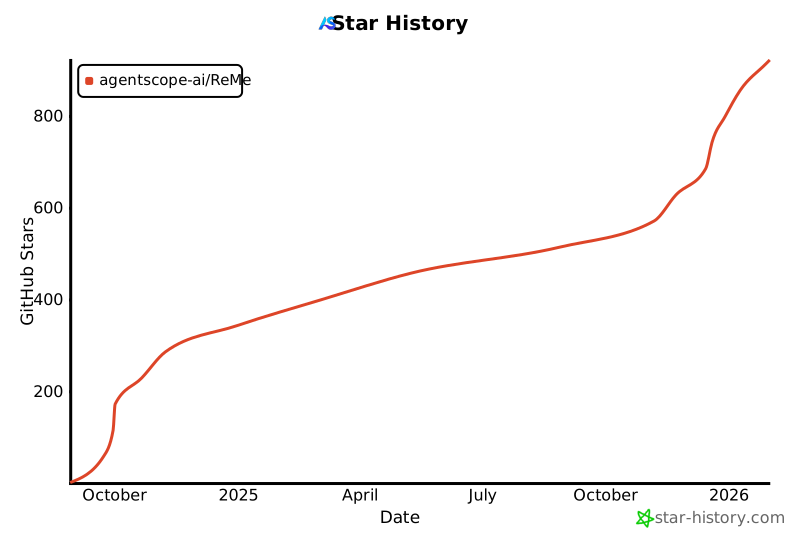](https://www.star-history.com/#agentscope-ai/ReMe&Date)
|
||||
|
||||
|
|
|
|||
659
README_ZH.md
659
README_ZH.md
|
|
@ -14,6 +14,7 @@
|
|||
<a href="./README.md"><img src="https://img.shields.io/badge/English-Click-yellow" alt="English"></a>
|
||||
<a href="./README_ZH.md"><img src="https://img.shields.io/badge/简体中文-点击查看-orange" alt="简体中文"></a>
|
||||
<a href="https://github.com/agentscope-ai/ReMe"><img src="https://img.shields.io/github/stars/agentscope-ai/ReMe?style=social" alt="GitHub Stars"></a>
|
||||
<a href="https://deepwiki.com/agentscope-ai/ReMe"><img src="https://img.shields.io/badge/DeepWiki-Ask_Devin-navy.svg" alt="DeepWiki"></a>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
|
|
@ -30,14 +31,28 @@
|
|||
|
||||
ReMe 让智能体拥有**真正的记忆力**——旧对话自动浓缩,重要信息持久保存,下次对话自动想起来。
|
||||
|
||||
<details>
|
||||
<summary><b>你可以用 ReMe 做什么</b></summary>
|
||||
|
||||
<br>
|
||||
|
||||
- **个人助理**:为 [CoPaw](https://github.com/agentscope-ai/CoPaw) 等智能体提供长期记忆,记住用户偏好和历史对话。
|
||||
- **编程助手**:记录代码风格偏好、项目上下文,跨会话保持一致的开发体验。
|
||||
- **客服机器人**:记录用户问题历史、偏好设置,提供个性化服务。
|
||||
- **任务自动化**:从历史任务中学习成功/失败模式,持续优化执行策略。
|
||||
- **知识问答**:构建可检索的知识库,支持语义搜索和精确匹配。
|
||||
- **多轮对话**:自动压缩长对话,在有限上下文窗口内保留关键信息。
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## 📁 基于文件的 ReMe
|
||||
## 📁 基于文件的记忆系统 (ReMeLight)
|
||||
|
||||
> 记忆即文件,文件即记忆
|
||||
|
||||
将**记忆视为文件**——可读、可编辑、可复制。
|
||||
[CoPaw](https://github.com/agentscope-ai/CoPaw) 通过继承 `ReMeLight` 实现了长期记忆和上下文的管理。
|
||||
|
||||
| 传统记忆系统 | File Based ReMe |
|
||||
|-----------|-----------------|
|
||||
|
|
@ -47,35 +62,323 @@ ReMe 让智能体拥有**真正的记忆力**——旧对话自动浓缩,重
|
|||
| 🚫 难迁移 | 📦 复制即迁移 |
|
||||
|
||||
```
|
||||
.reme/
|
||||
├── MEMORY.md # 长期记忆:用户偏好、项目配置等不常变的信息
|
||||
└── memory/
|
||||
└── YYYY-MM-DD.md # 每日日志:当天的工作记录,压缩时自动写入
|
||||
working_dir/
|
||||
├── MEMORY.md # 长期记忆:用户偏好等持久信息
|
||||
├── memory/
|
||||
│ └── YYYY-MM-DD.md # 每日日记:对话结束后自动写入
|
||||
└── tool_result/ # 超长工具输出缓存(自动管理,超期自动清理)
|
||||
└── <uuid>.txt
|
||||
```
|
||||
|
||||
### 核心能力
|
||||
|
||||
[ReMe File Based](reme/reme_fb.py) 是基于文件的记忆系统的核心类,就像一个**智能秘书**,帮你管理所有记忆相关的事务:
|
||||
[ReMeLight](reme/reme_light.py) 是该记忆系统的核心类,为 AI Agent 提供完整的记忆管理能力:
|
||||
|
||||
| 方法 | 功能 | 关键组件 |
|
||||
|-----------------|--------------|----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
|
||||
| `start` | 🚀 启动记忆系统 | [BaseFileStore](reme/core/file_store/base_file_store.py)(本地文件store)<br/>[BaseFileWatcher](reme/core/file_watcher/base_file_watcher.py)(文件监控)<br/>[BaseEmbeddingModel](reme/core/embedding/base_embedding_model.py)(Embedding 缓存) |
|
||||
| `close` | 📕 关闭并保存 | 关闭文件store、停止文件监控、保存 Embedding 缓存 |
|
||||
| `context_check` | 📏 检查上下文是否超限 | [ContextChecker](reme/memory/file_based/fb_context_checker.py) |
|
||||
| `compact` | 📦 压缩历史对话为摘要 | [Compactor](reme/memory/file_based/fb_compactor.py) |
|
||||
| `summary` | 📝 将重要记忆写入文件 | [Summarizer](reme/memory/file_based/fb_summarizer.py) |
|
||||
| `memory_search` | 🔍 语义搜索记忆 | [MemorySearch](reme/memory/tools/chunk/memory_search.py) |
|
||||
| `memory_get` | 📖 读取指定记忆文件 | [MemoryGet](reme/memory/tools/chunk/memory_get.py) |
|
||||
<table>
|
||||
<tr><th>类别</th><th>方法</th><th>功能</th><th>关键组件</th></tr>
|
||||
<tr><td rowspan="4">上下文管理</td><td><code>check_context</code></td><td>📊 检查上下文大小</td><td><a href="reme/memory/file_based/components/context_checker.py">ContextChecker</a> — 检查上下文是否超出阈值并拆分 Message</td></tr>
|
||||
<tr><td><code>compact_memory</code></td><td>📦 压缩历史对话为摘要</td><td><a href="reme/memory/file_based/components/compactor.py">Compactor</a> — ReActAgent 生成结构化上下文摘要</td></tr>
|
||||
<tr><td><code>compact_tool_result</code></td><td>✂️ 压缩超长工具输出</td><td><a href="reme/memory/file_based/components/tool_result_compactor.py">ToolResultCompactor</a> — 截断超长的工具调用结果并转存到 <code>tool_result/</code>,消息中保留文件引用</td></tr>
|
||||
<tr><td><code>pre_reasoning_hook</code></td><td>🔄 推理前预处理钩子</td><td>compact_tool_result + check_context + compact_memory + summary_memory(async)</td></tr>
|
||||
<tr><td rowspan="2">长期记忆</td><td><code>summary_memory</code></td><td>📝 将重要记忆写入文件</td><td><a href="reme/memory/file_based/components/summarizer.py">Summarizer</a> — ReActAgent + 文件工具(read / write / edit)</td></tr>
|
||||
<tr><td><code>memory_search</code></td><td>🔍 语义搜索记忆</td><td><a href="reme/memory/file_based/tools/memory_search.py">MemorySearch</a> — 向量 + BM25 混合检索</td></tr>
|
||||
<tr><td>-</td><td><code>start</code></td><td>🚀 启动记忆系统</td><td>初始化文件存储、文件监控、Embedding 缓存;清理过期工具结果文件</td></tr>
|
||||
<tr><td>-</td><td><code>close</code></td><td>📕 关闭并清理</td><td>清理工具结果文件、停止文件监控、保存 Embedding 缓存</td></tr>
|
||||
</table>
|
||||
|
||||
## 🗃️ 基于向量库的 ReMe
|
||||
---
|
||||
|
||||
### 🚀 快速开始
|
||||
|
||||
#### 安装
|
||||
|
||||
**从源码安装:**
|
||||
|
||||
```bash
|
||||
git clone https://github.com/agentscope-ai/ReMe.git
|
||||
cd ReMe
|
||||
pip install -e ".[light]"
|
||||
```
|
||||
|
||||
**更新到最新版本:**
|
||||
|
||||
```bash
|
||||
git pull
|
||||
pip install -e ".[light]"
|
||||
```
|
||||
|
||||
#### 环境变量
|
||||
|
||||
`ReMeLight` 环境变量配置 Embedding 和存储后端
|
||||
|
||||
| Variable | Description | Example |
|
||||
|----------------------|-------------------------|-----------------------------------------------------|
|
||||
| `LLM_API_KEY` | LLM API key | `sk-xxx` |
|
||||
| `LLM_BASE_URL` | LLM base URL | `https://dashscope.aliyuncs.com/compatible-mode/v1` |
|
||||
| `EMBEDDING_API_KEY` | Embedding API key (可选) | `sk-xxx` |
|
||||
| `EMBEDDING_BASE_URL` | Embedding base URL (可选) | `https://dashscope.aliyuncs.com/compatible-mode/v1` |
|
||||
|
||||
#### Python 使用
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
|
||||
from reme.reme_light import ReMeLight
|
||||
|
||||
|
||||
async def main():
|
||||
# 初始化 ReMeLight
|
||||
reme = ReMeLight(
|
||||
default_as_llm_config={"model_name": "qwen3.5-35b-a3b"},
|
||||
# default_embedding_model_config={"model_name": "text-embedding-v4"},
|
||||
default_file_store_config={"fts_enabled": True, "vector_enabled": False},
|
||||
)
|
||||
await reme.start()
|
||||
|
||||
messages = [...] # 对话消息列表
|
||||
|
||||
# 1. 压缩超长工具输出(防止工具结果撑爆上下文)
|
||||
messages = await reme.compact_tool_result(messages)
|
||||
|
||||
# 2. 将历史对话压缩为结构化摘要(可传入上轮摘要,实现增量更新)
|
||||
summary = await reme.compact_memory(
|
||||
messages=messages,
|
||||
previous_summary="",
|
||||
max_input_length=128000, # 模型上下文窗口(tokens)
|
||||
compact_ratio=0.7, # 达到 max_input_length * 0.7 时触发压缩
|
||||
language="zh", # 摘要语言(zh / "")
|
||||
)
|
||||
|
||||
# 3. 后台异步提交摘要任务(不阻塞对话,摘要写入 memory/YYYY-MM-DD.md)
|
||||
reme.add_async_summary_task(messages=messages)
|
||||
|
||||
# 4. 推理前预处理钩子(自动压缩工具结果 + 生成摘要)
|
||||
processed_messages, compressed_summary = await reme.pre_reasoning_hook(
|
||||
messages=messages,
|
||||
system_prompt="你是一个有帮助的 AI 助手。",
|
||||
compressed_summary="",
|
||||
max_input_length=128000,
|
||||
compact_ratio=0.7,
|
||||
memory_compact_reserve=10000,
|
||||
enable_tool_result_compact=True,
|
||||
tool_result_compact_keep_n=3,
|
||||
)
|
||||
|
||||
# 5. 语义搜索记忆(向量 + BM25 混合检索)
|
||||
result = await reme.memory_search(query="Python 版本偏好", max_results=5)
|
||||
|
||||
# 6. 创建会话内存实例(管理单次对话的上下文)
|
||||
from reme.memory.file_based.reme_in_memory_memory import ReMeInMemoryMemory
|
||||
memory = ReMeInMemoryMemory()
|
||||
for msg in messages:
|
||||
await memory.add(msg)
|
||||
token_stats = await memory.estimate_tokens(max_input_length=128000)
|
||||
print(f"当前上下文使用率: {token_stats['context_usage_ratio']:.1f}%")
|
||||
print(f"消息 Token 数: {token_stats['messages_tokens']}")
|
||||
print(f"预估总 Token 数: {token_stats['estimated_tokens']}")
|
||||
|
||||
# 7. 关闭前等待后台任务完成
|
||||
summary_result = await reme.await_summary_tasks()
|
||||
|
||||
# 关闭 ReMeLight
|
||||
await reme.close()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
asyncio.run(main())
|
||||
```
|
||||
|
||||
> 📂 完整示例代码:[test_reme_light.py](tests/light/test_reme_light.py)
|
||||
> 📋 运行结果示例:[test_reme_light_log.txt](tests/light/test_reme_light_log.txt)(223,838 tokens → 1,105 tokens,压缩率99.5%)
|
||||
|
||||
### 基于文件的 ReMeLight 记忆系统架构
|
||||
|
||||
[CoPaw MemoryManager](https://github.com/agentscope-ai/CoPaw/blob/main/src/copaw/agents/memory/memory_manager.py) 继承
|
||||
`ReMeLight`,将记忆能力集成到 Agent 推理流程中:
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
Agent[Agent] -->|每轮推理前| Hook[pre_reasoning_hook]
|
||||
Hook --> TC[compact_tool_result<br>压缩工具输出]
|
||||
TC --> CC[check_context<br>Token 计数]
|
||||
CC -->|超限| CM[compact_memory<br>生成摘要]
|
||||
CC -->|超限| SM[summary_memory<br>异步持久化]
|
||||
SM -->|ReAct + FileIO| Files[memory/*.md]
|
||||
Agent -->|主动调用| Search[memory_search<br>向量+BM25]
|
||||
Agent -->|会话内存| InMem[ReMeInMemoryMemory<br>Token感知内存]
|
||||
Files -.->|FileWatcher| Store[(FileStore<br>向量+FTS索引)]
|
||||
Search --> Store
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
#### 1. check_context — 上下文检查
|
||||
|
||||
[ContextChecker](reme/memory/file_based/components/context_checker.py) 基于 Token 计数判断上下文是否超限,自动拆分为「待压缩」和「保留」两组消息。
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
M[messages] --> H[AsMsgHandler<br>Token 计数]
|
||||
H --> C{total > threshold?}
|
||||
C -->|否| K[返回全部消息]
|
||||
C -->|是| S[从尾部向前保留<br>reserve tokens]
|
||||
S --> CP[messages_to_compact<br>早期消息]
|
||||
S --> KP[messages_to_keep<br>近期消息]
|
||||
S --> V{is_valid<br>工具调用对齐?}
|
||||
```
|
||||
|
||||
- **核心逻辑**:从尾部向前保留 `reserve` tokens,超出部分标记为待压缩
|
||||
- **完整性保证**:不拆分 user-assistant 对话对,不拆分 tool_use/tool_result 配对
|
||||
|
||||
---
|
||||
|
||||
#### 2. compact_memory — 对话压缩
|
||||
|
||||
[Compactor](reme/memory/file_based/components/compactor.py) 使用 ReActAgent 将历史对话压缩为**结构化上下文摘要**。
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
M[messages] --> H[AsMsgHandler<br>format_msgs_to_str]
|
||||
H --> A[ReActAgent<br>reme_compactor]
|
||||
P[previous_summary] -->|增量更新| A
|
||||
A --> S[结构化摘要<br>Goal/Progress/Decisions...]
|
||||
```
|
||||
|
||||
**摘要结构**(上下文检查点):
|
||||
|
||||
| 字段 | 说明 |
|
||||
|-----------------------|--------------------|
|
||||
| `## Goal` | 用户目标 |
|
||||
| `## Constraints` | 约束和偏好 |
|
||||
| `## Progress` | 任务进展 |
|
||||
| `## Key Decisions` | 关键决策 |
|
||||
| `## Next Steps` | 下一步计划 |
|
||||
| `## Critical Context` | 文件路径、函数名、错误信息等关键数据 |
|
||||
|
||||
- **增量更新**:传入 `previous_summary` 时,自动将新对话与旧摘要合并
|
||||
|
||||
---
|
||||
|
||||
#### 3. summary_memory — 记忆持久化
|
||||
|
||||
[Summarizer](reme/memory/file_based/components/summarizer.py) 采用 **ReAct + 文件工具** 模式,让 AI 自主决定写什么、写到哪。
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
M[messages] --> A[ReActAgent<br>reme_summarizer]
|
||||
A -->|read| R[读取 memory/YYYY-MM-DD.md]
|
||||
R --> T{思考: 如何合并?}
|
||||
T -->|write| W[覆盖写入]
|
||||
T -->|edit| E[精确替换]
|
||||
W --> F[memory/YYYY-MM-DD.md]
|
||||
E --> F
|
||||
```
|
||||
|
||||
**文件工具**([FileIO](reme/memory/file_based/tools/file_io.py)):
|
||||
|
||||
| 工具 | 功能 |
|
||||
|---------|---------|
|
||||
| `read` | 读取文件内容 |
|
||||
| `write` | 覆盖写入文件 |
|
||||
| `edit` | 精确匹配后替换 |
|
||||
|
||||
---
|
||||
|
||||
#### 4. compact_tool_result — 工具结果压缩
|
||||
|
||||
[ToolResultCompactor](reme/memory/file_based/components/tool_result_compactor.py) 解决工具输出过长导致上下文膨胀的问题。
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
M[messages] --> L{遍历 tool_result<br>len > threshold?}
|
||||
L -->|否| K[保留原样]
|
||||
L -->|是| T[truncate_text<br>截断到 threshold]
|
||||
T --> S[完整内容写入<br>tool_result/uuid.txt]
|
||||
S --> R[消息追加文件路径引用]
|
||||
R --> C[cleanup_expired_files<br>清理过期文件]
|
||||
```
|
||||
|
||||
- **自动清理**:过期文件(超过 `retention_days`)在 `start`/`close`/`compact_tool_result` 时自动删除
|
||||
|
||||
---
|
||||
|
||||
#### 5. memory_search — 记忆检索
|
||||
|
||||
[MemorySearch](reme/memory/file_based/tools/memory_search.py) 提供**向量 + BM25 混合检索**能力。
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
Q[query] --> E[Embedding<br>向量化]
|
||||
E --> V[vector_search<br>语义相似]
|
||||
Q --> B[BM25<br>关键词匹配]
|
||||
V -->|" weight: 0.7 "| M[去重 + 加权融合]
|
||||
B -->|" weight: 0.3 "| M
|
||||
M --> F[min_score 过滤]
|
||||
F --> R[Top-N 结果]
|
||||
```
|
||||
|
||||
- **融合机制**:向量权重 0.7 + BM25 权重 0.3,兼顾语义相似和精确匹配
|
||||
|
||||
---
|
||||
|
||||
#### 6. ReMeInMemoryMemory — 会话内存
|
||||
|
||||
[ReMeInMemoryMemory](reme/memory/file_based/reme_in_memory_memory.py) 扩展 AgentScope 的 `InMemoryMemory`,提供 Token
|
||||
感知的内存管理。
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
C[content] --> G[get_memory<br>exclude_mark=COMPRESSED]
|
||||
G --> F[排除已压缩消息]
|
||||
F --> P{prepend_summary?}
|
||||
P -->|是| S[头部插入 previous-summary]
|
||||
S --> O[输出 messages]
|
||||
P -->|否| O
|
||||
```
|
||||
|
||||
| 功能 | 说明 |
|
||||
|----------------------------------|-------------------|
|
||||
| `get_memory` | 按标记过滤,自动追加压缩摘要 |
|
||||
| `estimate_tokens` | 估算上下文 Token 用量 |
|
||||
| `state_dict` / `load_state_dict` | 状态序列化/反序列化(会话持久化) |
|
||||
|
||||
---
|
||||
|
||||
#### 7. pre_reasoning_hook — 推理前预处理
|
||||
|
||||
整合上述组件的统一入口,在每轮推理前自动管理上下文。
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
M[messages] --> TC[compact_tool_result<br>压缩超长工具输出]
|
||||
TC --> CC[check_context<br>计算剩余空间]
|
||||
CC --> D{messages_to_compact<br>非空?}
|
||||
D -->|否| K[返回原消息 + 原摘要]
|
||||
D -->|是| V{is_valid?}
|
||||
V -->|否| K
|
||||
V -->|是| CM[compact_memory<br>同步生成摘要]
|
||||
V -->|是| SM[add_async_summary_task<br>异步持久化]
|
||||
CM --> R[返回 messages_to_keep + 新摘要]
|
||||
```
|
||||
|
||||
**执行流程**:
|
||||
|
||||
1. `compact_tool_result` — 压缩超长工具输出
|
||||
2. `check_context` — 检查上下文是否超限
|
||||
3. `compact_memory` — 生成压缩摘要(同步)
|
||||
4. `summary_memory` — 持久化记忆(异步后台)
|
||||
|
||||
---
|
||||
|
||||
## 🗃️ 基于向量库的记忆系统
|
||||
|
||||
[ReMe Vector Based](reme/reme.py) 是基于向量库的记忆系统核心类,支持三种记忆类型的统一管理:
|
||||
|
||||
| 记忆类型 | 用途 | 使用场景 |
|
||||
|--------------|------------------|-------------|
|
||||
| **个人记忆** | 记录用户偏好、习惯 | `user_name` |
|
||||
| **任务/程序性记忆** | 记录任务执行经验、成功/失败模式 | `task_name` |
|
||||
| **工具记忆** | 记录工具使用经验、参数优化 | `tool_name` |
|
||||
| 记忆类型 | 用途 |
|
||||
|--------------|------------------|
|
||||
| **个人记忆** | 记录用户偏好、习惯 |
|
||||
| **任务/程序性记忆** | 记录任务执行经验、成功/失败模式 |
|
||||
| **工具记忆** | 记录工具使用经验、参数优化 |
|
||||
|
||||
### 核心能力
|
||||
|
||||
|
|
@ -89,177 +392,15 @@ ReMe 让智能体拥有**真正的记忆力**——旧对话自动浓缩,重
|
|||
| `delete_memory` | 🗑️ 删除记忆 | 删除指定记忆 |
|
||||
| `list_memory` | 📋 列出记忆 | 列出某类记忆,支持过滤和排序 |
|
||||
|
||||
---
|
||||
### 安装与环境变量
|
||||
|
||||
## 💻 ReMeCli:基于文件记忆的终端助手
|
||||
安装和环境变量配置与 [ReMeLight 一致](#安装),通过环境变量设置 API 密钥,可写在项目根目录的 `.env` 文件中。
|
||||
|
||||
<table border="0" cellspacing="0" cellpadding="0" style="border: none;">
|
||||
<tr style="border: none;">
|
||||
<td width="10%" style="border: none; vertical-align: middle; text-align: center;">
|
||||
<strong>马<br>上<br>有<br>钱</strong>
|
||||
</td>
|
||||
<td width="80%" style="border: none;">
|
||||
<video src="https://github.com/user-attachments/assets/befa7e40-63ba-4db2-8251-516024616e00" autoplay muted loop controls></video>
|
||||
</td>
|
||||
<td width="10%" style="border: none; vertical-align: middle; text-align: center;">
|
||||
<strong>马<br>到<br>成<br>功</strong>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### 什么时候会写记忆?
|
||||
|
||||
| 场景 | 写到哪 | 怎么触发 |
|
||||
|------------------|------------------------|----------------------|
|
||||
| 上下文超长自动压缩 | `memory/YYYY-MM-DD.md` | 后台自动 |
|
||||
| 用户执行 `/compact` | `memory/YYYY-MM-DD.md` | 手动压缩 + 后台保存 |
|
||||
| 用户执行 `/new` | `memory/YYYY-MM-DD.md` | 新对话 + 后台保存 |
|
||||
| 用户说"记住这个" | `MEMORY.md` 或日志 | Agent 用 `write` 工具写入 |
|
||||
| Agent 发现了重要决策/偏好 | `MEMORY.md` | Agent 主动写 |
|
||||
|
||||
### 记忆检索工具
|
||||
|
||||
| 方式 | 工具 | 什么时候用 | 举例 |
|
||||
|------|-----------------|------------|--------------------------|
|
||||
| 语义搜索 | `memory_search` | 不确定记在哪,模糊找 | "之前关于部署的讨论" |
|
||||
| 直接读 | `read` | 知道是哪天、哪个文件 | 读 `memory/2025-02-13.md` |
|
||||
|
||||
搜索用的是**向量 + BM25 混合检索**(向量权重 0.7,BM25 权重 0.3),无论自然语言还是精确关键词都能命中。
|
||||
|
||||
### 内置工具
|
||||
|
||||
| 工具 | 功能 | 细节 |
|
||||
|-----------------|----------|----------------------------------------|
|
||||
| `memory_search` | 搜记忆 | MEMORY.md 和 memory/*.md 里做向量+BM25 混合检索 |
|
||||
| `bash` | 跑命令 | 执行 bash 命令,有超时和输出截断 |
|
||||
| `ls` | 看目录 | 列目录结构 |
|
||||
| `read` | 读文件 | 文本和图片都行,支持分段读 |
|
||||
| `edit` | 改文件 | 精确匹配文本后替换 |
|
||||
| `write` | 写文件 | 创建或覆盖,自动建目录 |
|
||||
| `execute_code` | 跑 Python | 运行代码片段 |
|
||||
| `web_search` | 联网搜索 | 通过 Tavily |
|
||||
|
||||
---
|
||||
|
||||
## 🚀 快速开始
|
||||
|
||||
### 安装
|
||||
|
||||
```bash
|
||||
pip install -U reme-ai
|
||||
```
|
||||
|
||||
### 环境变量
|
||||
|
||||
API 密钥通过环境变量设置,可写在项目根目录的 `.env` 文件中:
|
||||
|
||||
| 环境变量 | 说明 | 示例 |
|
||||
|---------------------------|-----------------------|-----------------------------------------------------|
|
||||
| `REME_LLM_API_KEY` | LLM 的 API Key | `sk-xxx` |
|
||||
| `REME_LLM_BASE_URL` | LLM 的 Base URL | `https://dashscope.aliyuncs.com/compatible-mode/v1` |
|
||||
| `REME_EMBEDDING_API_KEY` | Embedding 的 API Key | `sk-xxx` |
|
||||
| `REME_EMBEDDING_BASE_URL` | Embedding 的 Base URL | `https://dashscope.aliyuncs.com/compatible-mode/v1` |
|
||||
| `TAVILY_API_KEY` | Tavily 搜索 API Key(可选) | `tvly-xxx` |
|
||||
|
||||
### 使用 ReMeCli
|
||||
|
||||
#### 启动 ReMeCli
|
||||
|
||||
```bash
|
||||
remecli config=cli
|
||||
```
|
||||
|
||||
#### ReMeCli 系统命令
|
||||
|
||||
> 马年彩蛋:`/horse` 触发——烟花、奔马动画和随机马年祝福。
|
||||
|
||||
对话里输入 `/` 开头的命令控制状态:
|
||||
|
||||
| 命令 | 说明 | 需等待响应 |
|
||||
|------------|---------------------|-------|
|
||||
| `/compact` | 手动压缩当前对话,同时后台存到长期记忆 | 是 |
|
||||
| `/new` | 开始新对话,历史后台保存到长期记忆 | 否 |
|
||||
| `/clear` | 清空一切,**不保存** | 否 |
|
||||
| `/history` | 看当前对话里未压缩的消息 | 否 |
|
||||
| `/help` | 看命令列表 | 否 |
|
||||
| `/exit` | 退出 | 否 |
|
||||
|
||||
**三个命令的区别**
|
||||
|
||||
| 命令 | 压缩摘要 | 长期记忆 | 消息历史 |
|
||||
|------------|-------|------|-------|
|
||||
| `/compact` | 生成新摘要 | 保存 | 保留最近的 |
|
||||
| `/new` | 清空 | 保存 | 清空 |
|
||||
| `/clear` | 清空 | 不保存 | 清空 |
|
||||
|
||||
> `/clear` 是真删,删了就没了,不会存到任何地方。
|
||||
|
||||
### 使用 ReMe Package
|
||||
|
||||
#### 基于文件的 ReMe
|
||||
### Python 使用
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
|
||||
from reme import ReMeFb
|
||||
|
||||
|
||||
async def main():
|
||||
# 初始化并启动
|
||||
reme = ReMeFb(
|
||||
default_llm_config={
|
||||
"backend": "openai", # 后端类型,支持 openai 兼容接口
|
||||
"model_name": "qwen3.5-plus", # 模型名称
|
||||
},
|
||||
default_file_store_config={
|
||||
"backend": "chroma", # 存储后端,支持 sqlite/chroma/local
|
||||
"fts_enabled": True, # 是否启用全文搜索
|
||||
"vector_enabled": False, # 是否启用向量搜索(无 embedding 服务可设为 False)
|
||||
},
|
||||
context_window_tokens=128000, # 模型上下文窗口大小(tokens)
|
||||
reserve_tokens=36000, # 预留给输出的 token 数量
|
||||
keep_recent_tokens=20000, # 保留最近消息的 token 数量
|
||||
vector_weight=0.7, # 向量搜索权重(0-1),用于混合搜索
|
||||
candidate_multiplier=3.0, # 候选结果倍数,用于召回更多候选项
|
||||
)
|
||||
await reme.start()
|
||||
|
||||
messages = [
|
||||
{"role": "user", "content": "我喜欢用 Python 3.12"},
|
||||
{"role": "assistant", "content": "好的,已记录你偏好 Python 3.12"},
|
||||
]
|
||||
|
||||
# 检查上下文是否超限
|
||||
result = await reme.context_check(messages)
|
||||
print(f"压缩结论: {result}")
|
||||
|
||||
# 压缩对话为摘要
|
||||
summary = await reme.compact(messages_to_summarize=messages)
|
||||
print(f"摘要: {summary}")
|
||||
|
||||
# 将重要记忆写入文件(ReAct Agent 自动操作)
|
||||
await reme.summary(messages=messages, date="2026-02-28")
|
||||
|
||||
# 语义搜索记忆
|
||||
results = await reme.memory_search(query="Python 版本偏好", max_results=5)
|
||||
print(f"搜索结果: {results}")
|
||||
|
||||
# 读取指定记忆文件
|
||||
content = await reme.memory_get(path="MEMORY.md")
|
||||
print(f"记忆内容: {content}")
|
||||
|
||||
# 关闭(保存 Embedding 缓存、停止文件监控)
|
||||
await reme.close()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
asyncio.run(main())
|
||||
```
|
||||
|
||||
#### 基于向量库的 ReMe
|
||||
|
||||
```python
|
||||
import asyncio
|
||||
from reme import ReMe
|
||||
|
||||
|
||||
|
|
@ -269,7 +410,7 @@ async def main():
|
|||
working_dir=".reme",
|
||||
default_llm_config={
|
||||
"backend": "openai",
|
||||
"model_name": "qwen3-30b-a3b-thinking-2507",
|
||||
"model_name": "qwen3.5-plus",
|
||||
},
|
||||
default_embedding_model_config={
|
||||
"backend": "openai",
|
||||
|
|
@ -346,102 +487,10 @@ if __name__ == "__main__":
|
|||
asyncio.run(main())
|
||||
```
|
||||
|
||||
## 🏛️ 技术架构
|
||||
|
||||
### 基于文件的 ReMe 核心架构
|
||||
|
||||
```mermaid
|
||||
graph TB
|
||||
User[用户 / Agent] --> ReMeFb[File based ReMe]
|
||||
ReMeFb --> ContextCheck[上下文检查]
|
||||
ReMeFb --> Compact[上下文压缩]
|
||||
ReMeFb --> Summary[记忆总结]
|
||||
ReMeFb --> Search[记忆检索]
|
||||
ContextCheck --> FbContextChecker[检查 Token 是否超限]
|
||||
Compact --> FbCompactor[压缩历史对话为摘要]
|
||||
Summary --> FbSummarizer[ReAct Agent + 文件工具]
|
||||
Search --> MemorySearch[向量 + BM25 混合检索]
|
||||
FbSummarizer --> FileTools[read / write / edit]
|
||||
FileTools --> MemoryFiles[memory/*.md]
|
||||
MemoryFiles -.->|文件变更| FileWatcher[异步文件监控]
|
||||
FileWatcher -->|更新索引| FileStore[本地数据库]
|
||||
MemorySearch --> FileStore
|
||||
```
|
||||
|
||||
#### 记忆总结:ReAct + 文件工具
|
||||
|
||||
[Summarizer](reme/memory/file_based/fb_summarizer.py) 是记忆总结的核心组件,它采用 **ReAct + 文件工具** 模式。
|
||||
### 技术架构
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
A[接收对话] --> B{思考: 有什么值得记录?}
|
||||
B --> C[行动: read memory/YYYY-MM-DD.md]
|
||||
C --> D{思考: 如何与现有内容合并?}
|
||||
D --> E[行动: edit 更新文件]
|
||||
E --> F{思考: 还有遗漏吗?}
|
||||
F -->|是| B
|
||||
F -->|否| G[完成]
|
||||
```
|
||||
|
||||
#### 文件工具集
|
||||
|
||||
Summarizer 配备了一套文件操作工具,让 AI 能够直接操作记忆文件:
|
||||
|
||||
| 工具 | 功能 | 使用场景 |
|
||||
|---------|--------|--------------|
|
||||
| `read` | 读取文件内容 | 查看现有记忆,避免重复 |
|
||||
| `write` | 覆盖写入文件 | 创建新记忆文件或大幅重构 |
|
||||
| `edit` | 编辑文件局部 | 追加新内容或修改特定部分 |
|
||||
|
||||
#### 上下文压缩
|
||||
|
||||
当对话过长时,[Compactor](reme/memory/file_based/fb_compactor.py) 负责将历史对话压缩为精华摘要——就像写**会议纪要**
|
||||
,把冗长的讨论浓缩成关键要点。
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
A[消息1..N] --> B[📦 压缩摘要]
|
||||
C[最近消息] --> D[保留原样]
|
||||
B --> E[新的上下文]
|
||||
D --> E
|
||||
```
|
||||
|
||||
压缩摘要包含继续工作所需的关键信息:
|
||||
|
||||
| 内容 | 说明 |
|
||||
|--------|---------------|
|
||||
| 🎯 目标 | 用户想要完成什么 |
|
||||
| ⚙️ 约束 | 用户提到的要求和偏好 |
|
||||
| 📈 进展 | 已完成/进行中/阻塞的任务 |
|
||||
| 🔑 决策 | 做出的决策及原因 |
|
||||
| 📌 上下文 | 文件路径、函数名等关键数据 |
|
||||
|
||||
#### 记忆检索
|
||||
|
||||
[MemorySearch](reme/memory/tools/chunk/memory_search.py) 提供**向量 + BM25 混合检索**能力,两种方式优势互补:
|
||||
|
||||
| 检索方式 | 优势 | 劣势 |
|
||||
|-------------|-----------------|----------------|
|
||||
| **向量语义** | 捕捉意义相近但措辞不同的内容 | 对精确 token 匹配较弱 |
|
||||
| **BM25 全文** | 精确 token 命中效果极佳 | 无法理解同义词和改写 |
|
||||
|
||||
**融合机制**:同时使用两路召回,按权重加权求和(向量 0.7 + BM25 0.3),确保无论是「自然语言提问」还是「精确查找」都能获得可靠结果。
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
Q[搜索查询] --> V[向量搜索 × 0.7]
|
||||
Q --> B[BM25 × 0.3]
|
||||
V --> M[去重 + 加权融合]
|
||||
B --> M
|
||||
M --> R[Top-N 结果]
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
### 基于向量库的 ReMe 核心架构
|
||||
|
||||
```mermaid
|
||||
graph TB
|
||||
User[用户 / Agent] --> ReMe[Vector Based ReMe]
|
||||
ReMe --> Summarize[记忆总结]
|
||||
ReMe --> Retrieve[记忆检索]
|
||||
|
|
@ -460,6 +509,41 @@ graph TB
|
|||
ToolRet --> VectorStore
|
||||
```
|
||||
|
||||
### 实验效果
|
||||
|
||||
Coming soon...
|
||||
|
||||
---
|
||||
|
||||
## 🧪 程序化记忆论文
|
||||
|
||||
> 我们的程序性(任务)记忆论文已在 [arXiv](https://arxiv.org/abs/2512.10696) 发布
|
||||
|
||||
### 🌍 [Appworld 实验](benchmark/appworld/quickstart.md)
|
||||
|
||||
我们在 Appworld 环境上使用 Qwen3-8B(非思考模式)进行评测:
|
||||
|
||||
| 方法 | Avg@4 | Pass@4 |
|
||||
|---------|---------------------|---------------------|
|
||||
| 无 ReMe | 0.1497 | 0.3285 |
|
||||
| 使用 ReMe | 0.1706 **(+2.09%)** | 0.3631 **(+3.46%)** |
|
||||
|
||||
Pass@K 衡量在生成 K 个候选中,至少一个成功完成任务(score=1)的概率。
|
||||
当前实验使用的是内部 AppWorld 环境,可能与对外版本存在轻微差异。
|
||||
|
||||
关于如何复现实验的更多细节,见 [quickstart.md](benchmark/appworld/quickstart.md)
|
||||
|
||||
### 🔧 [BFCL-V3 实验](benchmark/bfcl/quickstart.md)
|
||||
|
||||
我们在 BFCL-V3 multi-turn-base 任务(随机划分 50 train / 150 val)上,使用 Qwen3-8B(思考模式)进行评测:
|
||||
|
||||
| 方法 | Avg@4 | Pass@4 |
|
||||
|---------|---------------------|---------------------|
|
||||
| 无 ReMe | 0.4033 | 0.5955 |
|
||||
| 使用 ReMe | 0.4450 **(+4.17%)** | 0.6577 **(+6.22%)** |
|
||||
|
||||
关于如何复现实验的更多细节,见 [quickstart.md](benchmark/bfcl/quickstart.md)
|
||||
|
||||
## ⭐ 社区与支持
|
||||
|
||||
- **Star 与 Watch**:Star 可让更多智能体开发者发现 ReMe;Watch 可助你第一时间获知新版本与特性。
|
||||
|
|
@ -468,6 +552,14 @@ graph TB
|
|||
- **代码贡献**:欢迎任何形式的代码贡献,请参阅 [贡献指南](docs/contribution.md)。
|
||||
- **致谢**:感谢 OpenClaw、Mem0、MemU、CoPaw 等优秀的开源项目,为项目带来诸多启发与帮助。
|
||||
|
||||
### 贡献者
|
||||
|
||||
感谢所有为 ReMe 做出贡献的朋友们:
|
||||
|
||||
<a href="https://github.com/agentscope-ai/ReMe/graphs/contributors">
|
||||
<img src="https://contrib.rocks/image?repo=agentscope-ai/ReMe" alt="贡献者" />
|
||||
</a>
|
||||
|
||||
---
|
||||
|
||||
## 📄 引用
|
||||
|
|
@ -489,6 +581,13 @@ graph TB
|
|||
|
||||
---
|
||||
|
||||
## 🤔 为什么叫 ReMe?
|
||||
|
||||
ReMe 是 **Remember Me** 和 **Refine Me** 的缩写,寓意让 AI 智能体「记住我」并在交互中「精进自我」。我们希望 ReMe
|
||||
不只是一个冷冰冰的记忆模块,而是能让智能体真正理解用户、积累经验、持续进化的伙伴。
|
||||
|
||||
---
|
||||
|
||||
## 📈 Star 历史
|
||||
|
||||
[](https://www.star-history.com/#agentscope-ai/ReMe&Date)
|
||||
|
|
|
|||
|
|
@ -9,7 +9,7 @@ This guide helps you quickly set up and run AppWorld experiments with ReMe integ
|
|||
|
||||
```bash
|
||||
git clone https://github.com/agentscope-ai/ReMe.git
|
||||
cd ReMe/cookbook/appworld
|
||||
cd ReMe/benchmark/appworld
|
||||
```
|
||||
|
||||
### 2. Appworld Environment Setup
|
||||
|
|
@ -56,26 +56,16 @@ pip install .
|
|||
Launch the ReMe service to enable memory library functionality:
|
||||
|
||||
```bash
|
||||
reme \
|
||||
reme2 \
|
||||
backend=http \
|
||||
http.port=8002 \
|
||||
llm.default.model_name=qwen-max-latest \
|
||||
embedding_model.default.model_name=text-embedding-v4 \
|
||||
vector_store.default.backend=elasticsearch
|
||||
llms.default.model_name=qwen3-8b \
|
||||
embedding_models.default.model_name=text-embedding-v4 \
|
||||
vector_stores.default.backend=es \
|
||||
vector_stores.default.collection_name=appworld \
|
||||
vector_stores.default.hosts=http://xx.yy.zz.mm:nn
|
||||
```
|
||||
|
||||
add memories for appworld:
|
||||
```bash
|
||||
curl -X POST "http://0.0.0.0:8002/vector_store" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"workspace_id": "appworld",
|
||||
"action": "load",
|
||||
"path": "./docs/library"
|
||||
}'
|
||||
```
|
||||
Now you have loaded the ReMe memory library to enable memory-based agent!
|
||||
|
||||
### 4. Common Issues
|
||||
|
||||
**AppWorld data not found**: Ensure `appworld download data` completed successfully
|
||||
|
|
@ -95,21 +85,21 @@ python run_appworld.py
|
|||
```
|
||||
|
||||
**What this does:**
|
||||
- Runs AppWorld tasks on the development dataset
|
||||
- Runs AppWorld tasks on the test-normal set
|
||||
- Compares agent performance with ReMe memory (`use_memory=True`) vs without memory
|
||||
- Uses multiple workers for parallel processing
|
||||
- Runs each task multiple times for statistical significance
|
||||
- Results are automatically saved to `./exp_result/` directory
|
||||
|
||||
**Configuration options in `run_appworld.py`:**
|
||||
- `max_workers`: Number of parallel workers (default: 8)
|
||||
- `num_runs`: Number of times each task is repeated (default: 1)
|
||||
- `max_workers`: Number of parallel workers (default: 16)
|
||||
- `num_runs`: Number of times each task is repeated (default: 4)
|
||||
- `batch_size`: Number of concurrent tasks per batch (default: 8)
|
||||
- `num_trials`: Maximum number of self-reflections, failure-aware reflection mechanism is triggered when num_trials>1 (default: 1)
|
||||
- `model_name`: Task execution model
|
||||
- `use_memory`: Whether to use ReMe memory library
|
||||
- `use_memory_addition`: Whether to enable selective addition
|
||||
- `use_memory_deletion`: Whether to enable utility-based deletion
|
||||
- `model_name`: Task execution model (default: "qwen3-8b")
|
||||
- `use_memory`: Whether to use ReMe memory library (default: True)
|
||||
- `use_memory_addition`: Whether to enable selective addition (default: False)
|
||||
- `use_memory_deletion`: Whether to enable utility-based deletion (default: False)
|
||||
|
||||
### 2. View Experiment Results
|
||||
|
||||
206
benchmark/bfcl/default_ids.py
Normal file
206
benchmark/bfcl/default_ids.py
Normal file
|
|
@ -0,0 +1,206 @@
|
|||
# pylint: disable=C0114
|
||||
DEFAULT_TRAIN_IDS: set[str] = {
|
||||
"multi_turn_base_102",
|
||||
"multi_turn_base_107",
|
||||
"multi_turn_base_110",
|
||||
"multi_turn_base_114",
|
||||
"multi_turn_base_115",
|
||||
"multi_turn_base_118",
|
||||
"multi_turn_base_122",
|
||||
"multi_turn_base_123",
|
||||
"multi_turn_base_128",
|
||||
"multi_turn_base_13",
|
||||
"multi_turn_base_130",
|
||||
"multi_turn_base_132",
|
||||
"multi_turn_base_133",
|
||||
"multi_turn_base_143",
|
||||
"multi_turn_base_144",
|
||||
"multi_turn_base_146",
|
||||
"multi_turn_base_15",
|
||||
"multi_turn_base_158",
|
||||
"multi_turn_base_169",
|
||||
"multi_turn_base_17",
|
||||
"multi_turn_base_172",
|
||||
"multi_turn_base_176",
|
||||
"multi_turn_base_182",
|
||||
"multi_turn_base_187",
|
||||
"multi_turn_base_197",
|
||||
"multi_turn_base_199",
|
||||
"multi_turn_base_22",
|
||||
"multi_turn_base_23",
|
||||
"multi_turn_base_24",
|
||||
"multi_turn_base_36",
|
||||
"multi_turn_base_40",
|
||||
"multi_turn_base_44",
|
||||
"multi_turn_base_47",
|
||||
"multi_turn_base_48",
|
||||
"multi_turn_base_5",
|
||||
"multi_turn_base_51",
|
||||
"multi_turn_base_59",
|
||||
"multi_turn_base_63",
|
||||
"multi_turn_base_65",
|
||||
"multi_turn_base_66",
|
||||
"multi_turn_base_67",
|
||||
"multi_turn_base_68",
|
||||
"multi_turn_base_70",
|
||||
"multi_turn_base_75",
|
||||
"multi_turn_base_77",
|
||||
"multi_turn_base_78",
|
||||
"multi_turn_base_79",
|
||||
"multi_turn_base_81",
|
||||
"multi_turn_base_83",
|
||||
"multi_turn_base_93",
|
||||
}
|
||||
|
||||
DEFAULT_VAL_IDS: set[str] = {
|
||||
"multi_turn_base_0",
|
||||
"multi_turn_base_1",
|
||||
"multi_turn_base_10",
|
||||
"multi_turn_base_100",
|
||||
"multi_turn_base_101",
|
||||
"multi_turn_base_103",
|
||||
"multi_turn_base_104",
|
||||
"multi_turn_base_105",
|
||||
"multi_turn_base_106",
|
||||
"multi_turn_base_108",
|
||||
"multi_turn_base_109",
|
||||
"multi_turn_base_11",
|
||||
"multi_turn_base_111",
|
||||
"multi_turn_base_112",
|
||||
"multi_turn_base_113",
|
||||
"multi_turn_base_116",
|
||||
"multi_turn_base_117",
|
||||
"multi_turn_base_119",
|
||||
"multi_turn_base_12",
|
||||
"multi_turn_base_120",
|
||||
"multi_turn_base_121",
|
||||
"multi_turn_base_124",
|
||||
"multi_turn_base_125",
|
||||
"multi_turn_base_126",
|
||||
"multi_turn_base_127",
|
||||
"multi_turn_base_129",
|
||||
"multi_turn_base_131",
|
||||
"multi_turn_base_134",
|
||||
"multi_turn_base_135",
|
||||
"multi_turn_base_136",
|
||||
"multi_turn_base_137",
|
||||
"multi_turn_base_138",
|
||||
"multi_turn_base_139",
|
||||
"multi_turn_base_14",
|
||||
"multi_turn_base_140",
|
||||
"multi_turn_base_141",
|
||||
"multi_turn_base_142",
|
||||
"multi_turn_base_145",
|
||||
"multi_turn_base_147",
|
||||
"multi_turn_base_148",
|
||||
"multi_turn_base_149",
|
||||
"multi_turn_base_150",
|
||||
"multi_turn_base_151",
|
||||
"multi_turn_base_152",
|
||||
"multi_turn_base_153",
|
||||
"multi_turn_base_154",
|
||||
"multi_turn_base_155",
|
||||
"multi_turn_base_156",
|
||||
"multi_turn_base_157",
|
||||
"multi_turn_base_159",
|
||||
"multi_turn_base_16",
|
||||
"multi_turn_base_160",
|
||||
"multi_turn_base_161",
|
||||
"multi_turn_base_162",
|
||||
"multi_turn_base_163",
|
||||
"multi_turn_base_164",
|
||||
"multi_turn_base_165",
|
||||
"multi_turn_base_166",
|
||||
"multi_turn_base_167",
|
||||
"multi_turn_base_168",
|
||||
"multi_turn_base_170",
|
||||
"multi_turn_base_171",
|
||||
"multi_turn_base_173",
|
||||
"multi_turn_base_174",
|
||||
"multi_turn_base_175",
|
||||
"multi_turn_base_177",
|
||||
"multi_turn_base_178",
|
||||
"multi_turn_base_179",
|
||||
"multi_turn_base_18",
|
||||
"multi_turn_base_180",
|
||||
"multi_turn_base_181",
|
||||
"multi_turn_base_183",
|
||||
"multi_turn_base_184",
|
||||
"multi_turn_base_185",
|
||||
"multi_turn_base_186",
|
||||
"multi_turn_base_188",
|
||||
"multi_turn_base_189",
|
||||
"multi_turn_base_19",
|
||||
"multi_turn_base_190",
|
||||
"multi_turn_base_191",
|
||||
"multi_turn_base_192",
|
||||
"multi_turn_base_193",
|
||||
"multi_turn_base_194",
|
||||
"multi_turn_base_195",
|
||||
"multi_turn_base_196",
|
||||
"multi_turn_base_198",
|
||||
"multi_turn_base_2",
|
||||
"multi_turn_base_20",
|
||||
"multi_turn_base_21",
|
||||
"multi_turn_base_25",
|
||||
"multi_turn_base_26",
|
||||
"multi_turn_base_27",
|
||||
"multi_turn_base_28",
|
||||
"multi_turn_base_29",
|
||||
"multi_turn_base_3",
|
||||
"multi_turn_base_30",
|
||||
"multi_turn_base_31",
|
||||
"multi_turn_base_32",
|
||||
"multi_turn_base_33",
|
||||
"multi_turn_base_34",
|
||||
"multi_turn_base_35",
|
||||
"multi_turn_base_37",
|
||||
"multi_turn_base_38",
|
||||
"multi_turn_base_39",
|
||||
"multi_turn_base_4",
|
||||
"multi_turn_base_41",
|
||||
"multi_turn_base_42",
|
||||
"multi_turn_base_43",
|
||||
"multi_turn_base_45",
|
||||
"multi_turn_base_46",
|
||||
"multi_turn_base_49",
|
||||
"multi_turn_base_50",
|
||||
"multi_turn_base_52",
|
||||
"multi_turn_base_53",
|
||||
"multi_turn_base_54",
|
||||
"multi_turn_base_55",
|
||||
"multi_turn_base_56",
|
||||
"multi_turn_base_57",
|
||||
"multi_turn_base_58",
|
||||
"multi_turn_base_6",
|
||||
"multi_turn_base_60",
|
||||
"multi_turn_base_61",
|
||||
"multi_turn_base_62",
|
||||
"multi_turn_base_64",
|
||||
"multi_turn_base_69",
|
||||
"multi_turn_base_7",
|
||||
"multi_turn_base_71",
|
||||
"multi_turn_base_72",
|
||||
"multi_turn_base_73",
|
||||
"multi_turn_base_74",
|
||||
"multi_turn_base_76",
|
||||
"multi_turn_base_8",
|
||||
"multi_turn_base_80",
|
||||
"multi_turn_base_82",
|
||||
"multi_turn_base_84",
|
||||
"multi_turn_base_85",
|
||||
"multi_turn_base_86",
|
||||
"multi_turn_base_87",
|
||||
"multi_turn_base_88",
|
||||
"multi_turn_base_89",
|
||||
"multi_turn_base_9",
|
||||
"multi_turn_base_90",
|
||||
"multi_turn_base_91",
|
||||
"multi_turn_base_92",
|
||||
"multi_turn_base_94",
|
||||
"multi_turn_base_95",
|
||||
"multi_turn_base_96",
|
||||
"multi_turn_base_97",
|
||||
"multi_turn_base_98",
|
||||
"multi_turn_base_99",
|
||||
}
|
||||
|
|
@ -114,6 +114,9 @@ def post_to_summarizer(trajectories: List[Any], service_url: str) -> Dict[str, A
|
|||
|
||||
request_data = {
|
||||
"trajectories": trajectory_dicts,
|
||||
"success_threshold": 1.0,
|
||||
"enable_soft_comparison": True,
|
||||
"validation_threshold": 0.5,
|
||||
}
|
||||
|
||||
try:
|
||||
|
|
@ -156,6 +159,9 @@ def process_trajectories_with_threads(
|
|||
results.append(result)
|
||||
if "memory_list" in result["metadata"]:
|
||||
print(f'✅ Group {group_index} processed: {result["metadata"].get("memory_list", 0)}')
|
||||
memory_list = result["metadata"].get("memory_list", [])
|
||||
response = requests.post(url=f"{service_url}/add_task_memory", json={"memory_list": memory_list})
|
||||
response.raise_for_status()
|
||||
else:
|
||||
print(f"❌ Group {group_index} processed: error")
|
||||
except Exception as e:
|
||||
|
|
@ -174,7 +180,7 @@ def main():
|
|||
"""Main function to convert JSONL to memories using ReMe service."""
|
||||
parser = argparse.ArgumentParser(description="Convert JSONL to memories using ReMe service")
|
||||
parser.add_argument("--jsonl_file", type=str, required=True, help="Path to the JSONL file")
|
||||
parser.add_argument("--service_url", type=str, default="http://localhost:8001", help="ReMe service URL")
|
||||
parser.add_argument("--service_url", type=str, default="http://localhost:8002", help="ReMe service URL")
|
||||
parser.add_argument("--output_file", type=str, help="Output file to save results (optional)")
|
||||
parser.add_argument("--n_threads", type=int, default=4, help="Number of threads for processing")
|
||||
|
||||
|
|
@ -226,21 +232,4 @@ def main():
|
|||
|
||||
|
||||
if __name__ == "__main__":
|
||||
import sys
|
||||
|
||||
if len(sys.argv) > 1:
|
||||
main()
|
||||
else:
|
||||
print("Running in compatibility mode...")
|
||||
with open("exp_result/qwen3-8b/with_think/bfcl-multi-turn-base-train_wo-exp.jsonl", "r") as f:
|
||||
data = [json.loads(line) for line in f]
|
||||
|
||||
grouped_trajectories = group_trajectories_by_task_id(data)
|
||||
print(f"Total groups: {len(grouped_trajectories)}")
|
||||
|
||||
results = process_trajectories_with_threads(
|
||||
grouped_trajectories,
|
||||
"http://localhost:8001",
|
||||
n_threads=4,
|
||||
)
|
||||
print(f"Processed {len(results)} groups")
|
||||
main()
|
||||
|
|
|
|||
|
|
@ -1,30 +0,0 @@
|
|||
"""Load the library data and convert them to the new format"""
|
||||
|
||||
import json
|
||||
|
||||
with open("../../file_vector_store/bfcl_test.jsonl", "r", encoding="utf-8") as f:
|
||||
bfcl = [json.loads(line) for line in f]
|
||||
|
||||
new_bfcl = []
|
||||
for exp in bfcl:
|
||||
new_exp = {}
|
||||
new_exp["workspace_id"] = exp["workspace_id"]
|
||||
new_exp["memory_id"] = exp["unique_id"]
|
||||
new_exp["memory_type"] = exp["metadata"]["memory_type"]
|
||||
|
||||
new_exp["when_to_use"] = exp["content"]
|
||||
new_exp["content"] = exp["metadata"]["content"]
|
||||
new_exp["score"] = exp["metadata"]["score"]
|
||||
|
||||
new_exp["time_created"] = exp["metadata"]["time_created"]
|
||||
new_exp["time_modified"] = exp["metadata"]["time_modified"]
|
||||
new_exp["author"] = exp["metadata"]["author"]
|
||||
|
||||
new_exp["metadata"] = exp["metadata"]["metadata"]
|
||||
new_exp["metadata"]["utility"] = 0
|
||||
new_exp["metadata"]["freq"] = 0
|
||||
|
||||
new_bfcl.append(new_exp)
|
||||
|
||||
with open("../../library/bfcl_test.jsonl", "w", encoding="utf-8") as f:
|
||||
f.writelines(json.dumps(item, ensure_ascii=False) + "\n" for item in new_bfcl)
|
||||
129
benchmark/bfcl/quickstart.md
Normal file
129
benchmark/bfcl/quickstart.md
Normal file
|
|
@ -0,0 +1,129 @@
|
|||
# BFCL
|
||||
Experiment Quick Start Guide
|
||||
|
||||
This guide helps you quickly set up and run BFCL experiments with ReMe integration.
|
||||
|
||||
## Env Setup
|
||||
|
||||
### 1. BFCL installation
|
||||
|
||||
#### Clone the repository
|
||||
```bash
|
||||
cd ReMe/benchmark/bfcl
|
||||
git clone https://github.com/ShishirPatil/gorilla.git
|
||||
cd gorilla
|
||||
git checkout ea13468
|
||||
```
|
||||
|
||||
#### Change directory to the `berkeley-function-call-leaderboard`
|
||||
```bash
|
||||
cd berkeley-function-call-leaderboard
|
||||
```
|
||||
|
||||
#### Install the package in editable mode
|
||||
```bash
|
||||
pip install -e .
|
||||
cd ../..
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
#### Move the dataset to the data folder under bfcl
|
||||
```bash
|
||||
cp -r gorilla/berkeley-function-call-leaderboard/bfcl_eval/data ./
|
||||
```
|
||||
|
||||
#### Preprocess the data to get the suitable data format
|
||||
```bash
|
||||
python preprocess.py
|
||||
```
|
||||
|
||||
**Note**: The original BFCL data is designed as a benchmark dataset and does not have a train/validation split, you can use ``split_into_trainval.py`` to split data into train and validation sets.
|
||||
|
||||
```bash
|
||||
python split_into_trainval.py --input ./data/multiturn_data_base.jsonl --train ./data/multiturn_data_base_train.jsonl --val ./data/multiturn_data_base_val.jsonl
|
||||
```
|
||||
|
||||
### 2. Start ReMe Service
|
||||
|
||||
After collecting trajectories, Launch the ReMe service (make sure you have installed ReMe environment, if not please follow the steps in the [ReMe Installation Guide](https://github.com/agentscope-ai/ReMe/blob/main/doc/README.md) to install):
|
||||
|
||||
```bash
|
||||
reme2 \
|
||||
backend=http \
|
||||
http.port=8002 \
|
||||
llms.default.model_name=qwen3-8b \
|
||||
embedding_models.default.model_name=text-embedding-v4 \
|
||||
vector_stores.default.backend=local \
|
||||
vector_stores.default.collection_name=bfcl
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>Option: init the task memory pool from scratch</summary>
|
||||
|
||||
- First, collect agent trajectories on training data set without task memory:
|
||||
|
||||
```bash
|
||||
# important: num_runs = 8, use_memory = False, experiment_suffix="wo-memory", data_path="data/multiturn_data_base_train.jsonl"
|
||||
python run_bfcl.py
|
||||
```
|
||||
|
||||
- Second, using ReMe to construct the initial task memory pool:
|
||||
```bash
|
||||
python init_task_memory_pool.py --jsonl_file ./exp_result/qwen3-8b/with_think/bfcl-multi-turn-base_wo-memory.jsonl
|
||||
```
|
||||
|
||||
> Parameters:
|
||||
> `jsonl_file`: Path to the collloaded trajectories
|
||||
> `service_url`: ReMe service URL (default: `http://localhost:8002`)
|
||||
> `n_threads`: Number of threads for processing
|
||||
> `output_file`: Output file to save results (optional)
|
||||
|
||||
Now you have inited the task memory pool using `local` backend. Then, run the following `curl` command to dump the memory library:
|
||||
```bash
|
||||
curl -X POST "http://0.0.0.0:8002/dump_memory" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"dump_file_path": "./library/bfcl.jsonl",
|
||||
}'
|
||||
```
|
||||
|
||||
- Next time, you can import this previously exported task memory data to populate the new started workspace with existing knowledge:
|
||||
```bash
|
||||
curl -X POST "http://0.0.0.0:8002/load_memory" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"load_file_path": "./library/bfcl.jsonl",
|
||||
"clear_existing": true
|
||||
}'
|
||||
```
|
||||
</details>
|
||||
|
||||
### 3. Run Experiments on Validation Set
|
||||
|
||||
Run you can compare agent performance on the validation set with task memory (`use_memory=True`) and without task memory:
|
||||
|
||||
```bash
|
||||
# remember to change the configuration options, e.g., `data_path=./data/multiturn_data_base_val.jsonl`
|
||||
python run_bfcl.py
|
||||
```
|
||||
|
||||
**Note**:
|
||||
- `max_workers`: Number of parallel workers
|
||||
- `num_runs`: Number of times each task is repeated
|
||||
- `model_name`: LLM model name
|
||||
- `enable_thinking`: Control the model's thinking mode
|
||||
- `data_path`: Path to the training dataset (default: `./data/multiturn_data_base_val.jsonl`)
|
||||
- `answer_path`: Path to the possible answer, which are used to evaluate the model's output function (default: `./data/possible_answer`)
|
||||
- Results are automatically saved to `./exp_result/{model_name}/{no_think/with_think}` directory
|
||||
|
||||
After running experiments, analyze the statistical results:
|
||||
|
||||
```bash
|
||||
python run_exp_statistic.py
|
||||
```
|
||||
|
||||
**What this script does:**
|
||||
- Processes all result files in `./exp_result/`
|
||||
- Calculates best@k&pass@k metrics for different k values
|
||||
- Generates a summary table showing performance comparisons
|
||||
- Saves results to `experiment_summary.csv`
|
||||
|
|
@ -2,4 +2,5 @@ jinja2
|
|||
loguru
|
||||
openai
|
||||
ray
|
||||
pandas
|
||||
pandas
|
||||
soundfile
|
||||
|
|
@ -131,7 +131,7 @@ def main():
|
|||
run_agent(
|
||||
max_workers=max_workers,
|
||||
model_name=model_name,
|
||||
dataset_name="bfcl-multi-turn-base",
|
||||
dataset_name="bfcl-multi-turn-base-val",
|
||||
experiment_suffix="w-fixed-memory",
|
||||
data_path="data/multiturn_data_base_val.jsonl",
|
||||
answer_path=Path("data/possible_answer"),
|
||||
|
|
|
|||
|
|
@ -141,7 +141,7 @@ def run_exp_statistic():
|
|||
|
||||
# Sort columns by the number in column name (best@8, best@4, best@2, best@1)
|
||||
# best_columns = [col for col in df.columns if col.startswith('best@')]
|
||||
best_columns = df.columns
|
||||
best_columns = list(df.columns)
|
||||
best_columns.sort(key=lambda x: x, reverse=False)
|
||||
df = df[best_columns]
|
||||
|
||||
|
|
|
|||
|
|
@ -4,16 +4,46 @@ import argparse
|
|||
import json
|
||||
import random
|
||||
|
||||
from default_ids import DEFAULT_TRAIN_IDS, DEFAULT_VAL_IDS
|
||||
|
||||
def split_jsonl(input_file, train_file, val_file, ratio=0.8):
|
||||
|
||||
def split_jsonl(
|
||||
input_file: str,
|
||||
train_file: str,
|
||||
val_file: str,
|
||||
ratio: float = 0.75,
|
||||
random_split: bool = False,
|
||||
) -> None:
|
||||
"""Split the JSONL file into train and validation sets."""
|
||||
with open(input_file, "r", encoding="utf-8") as f:
|
||||
data = [json.loads(line) for line in f]
|
||||
random.shuffle(data)
|
||||
|
||||
split_idx = int(len(data) * ratio)
|
||||
train_data = data[:split_idx]
|
||||
val_data = data[split_idx:]
|
||||
if random_split:
|
||||
random.shuffle(data)
|
||||
split_idx = int(len(data) * ratio)
|
||||
train_data = data[:split_idx]
|
||||
val_data = data[split_idx:]
|
||||
else:
|
||||
train_data = []
|
||||
val_data = []
|
||||
unknown_ids: list[str] = []
|
||||
for obj in data:
|
||||
if "id" not in obj:
|
||||
raise ValueError(f"Missing 'id' field in input file: {input_file}")
|
||||
obj_id = str(obj["id"])
|
||||
if obj_id in DEFAULT_TRAIN_IDS:
|
||||
train_data.append(obj)
|
||||
elif obj_id in DEFAULT_VAL_IDS:
|
||||
val_data.append(obj)
|
||||
else:
|
||||
unknown_ids.append(obj_id)
|
||||
|
||||
if len(train_data) + len(val_data) != len(data):
|
||||
missing = len(data) - (len(train_data) + len(val_data))
|
||||
examples = ", ".join(unknown_ids) if unknown_ids else "(none)"
|
||||
raise ValueError(
|
||||
f"{missing} samples in {input_file} not found in train_ref/val_ref id sets. Examples: {examples}",
|
||||
)
|
||||
|
||||
with open(train_file, "w", encoding="utf-8") as f:
|
||||
for item in train_data:
|
||||
|
|
@ -29,6 +59,11 @@ if __name__ == "__main__":
|
|||
parser.add_argument("--train", required=True, help="Path to output train file")
|
||||
parser.add_argument("--val", required=True, help="Path to output validation file")
|
||||
parser.add_argument("--ratio", type=float, default=0.5, help="Train ratio (default: 0.8)")
|
||||
|
||||
parser.add_argument(
|
||||
"--random",
|
||||
action="store_true",
|
||||
help="Whether to randomly split input into train/val. "
|
||||
"If false, split strictly by default train/val id sets (see default_ids.py).",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
split_jsonl(args.input, args.train, args.val, args.ratio)
|
||||
split_jsonl(args.input, args.train, args.val, args.ratio, args.random)
|
||||
|
|
|
|||
5
benchmark/halumem/eval_scripts.sh
Executable file
5
benchmark/halumem/eval_scripts.sh
Executable file
|
|
@ -0,0 +1,5 @@
|
|||
clear && python benchmark/halumem/eval_reme.py \
|
||||
--data_path /Users/yuli/workspace/HaluMem/data/HaluMem-Medium.jsonl \
|
||||
--reme_model_name qwen3.5-plus \
|
||||
--batch_size 10000 \
|
||||
--algo_version default
|
||||
1107
benchmark/locomo/eval_reme.py
Normal file
1107
benchmark/locomo/eval_reme.py
Normal file
File diff suppressed because it is too large
Load diff
180
benchmark/locomo/eval_reme.yaml
Normal file
180
benchmark/locomo/eval_reme.yaml
Normal file
|
|
@ -0,0 +1,180 @@
|
|||
TEMPLATE_MEMOS: |
|
||||
Memories for user {user_id}:
|
||||
{memories}
|
||||
|
||||
PROMPT_MEMZERO_JSON: |
|
||||
# CONTEXT:
|
||||
{context}
|
||||
|
||||
# CONTEXT PRIORITY:
|
||||
When the context contains information from multiple sources, follow this strict priority order:
|
||||
1. **Historical Dialogue** (highest priority) - Direct conversation content
|
||||
2. **Extracted Memories** (medium priority) - Summarized memory points
|
||||
3. **User Profile** (lowest priority) - General user information
|
||||
|
||||
# Question:
|
||||
{question}
|
||||
|
||||
# INSTRUCTIONS:
|
||||
1. Carefully analyze all provided memories (facts and entities)
|
||||
2. Pay special attention to the timestamps (event_time) to determine when events occurred
|
||||
3. If the question asks about a specific event or fact, look for direct evidence in the memories
|
||||
4. If the memories contain contradictory information, prioritize the most recent memory
|
||||
5. Always convert relative time references to specific dates, months, or years
|
||||
6. Be as specific as possible when talking about people, places, and events
|
||||
7. Timestamps in memories represent the time the event was mentioned in a message, not the actual time the event occurred
|
||||
|
||||
|
||||
# OUTPUT FORMAT:
|
||||
Please provide your response in the following JSON format:
|
||||
|
||||
```json
|
||||
{{
|
||||
"reasoning": "reasoning content",
|
||||
"answer": "Provide a detailed answer"
|
||||
}}
|
||||
```
|
||||
|
||||
SYSTEM_PROMPT: |
|
||||
You are an expert grader that determines if answers to questions match a gold standard answer
|
||||
|
||||
USER_PROMPT: |
|
||||
Your task is to label an answer to a question as 'CORRECT' or 'WRONG'. You will be given the following data:
|
||||
(1) a question (posed by one user to another user),
|
||||
(2) a 'gold' (ground truth) answer,
|
||||
(3) a generated answer
|
||||
which you will score as CORRECT/WRONG.
|
||||
|
||||
The point of the question is to ask about something one user should know about the other user based on their prior conversations.
|
||||
The gold answer will usually be a concise and short answer that includes the referenced topic, for example:
|
||||
Question: Do you remember what I got the last time I went to Hawaii?
|
||||
Gold answer: A shell necklace
|
||||
The generated answer might be much longer, but you should be generous with your grading - as long as it touches on the same topic as the gold answer, it should be counted as CORRECT.
|
||||
|
||||
For time related questions, the gold answer will be a specific date, month, year, etc. The generated answer might be much longer or use relative time references (like "last Tuesday" or "next month"), but you should be generous with your grading - as long as it refers to the same date or time period as the gold answer, it should be counted as CORRECT. Even if the format differs (e.g., "May 7th" vs "7 May"), consider it CORRECT if it's the same date.
|
||||
|
||||
Now it's time for the real question:
|
||||
Question: {question}
|
||||
Gold answer: {golden_answer}
|
||||
Generated answer: {generated_answer}
|
||||
|
||||
First, provide a short (one sentence) explanation of your reasoning, then finish with CORRECT or WRONG.
|
||||
Do NOT include both CORRECT and WRONG in your response, or it will break the evaluation script.
|
||||
|
||||
Just return the label CORRECT or WRONG in a json format with the key as "label".
|
||||
|
||||
user_message_summary_1: |
|
||||
You are a Memory Agent responsible for managing {memory_type} memories about {memory_target}.
|
||||
|
||||
## Latest Conversation
|
||||
Format: round<index> [<timestamp>] <role/name>: <content>
|
||||
{context}
|
||||
|
||||
## Task
|
||||
### Step 1: Create Memory Draft
|
||||
Use `add_draft_and_retrieve_similar_memory` to create a memory draft list based on the latest conversation.
|
||||
- For each memory draft, fill in the required parameters:
|
||||
* `message_time`: timestamp from the conversation (e.g., '2020-01-01 00:00:00')
|
||||
* `memory_content`: concise memory content extracted from the conversation
|
||||
- Use actual names from the conversation (e.g., "Bob likes apples") instead of generic references (e.g., "user likes apples")
|
||||
- Extract all important information comprehensively—do not miss critical details, but avoid any fabrications or unfounded assumptions
|
||||
- The tool will retrieve similar historical memories via vector search to help you in Step 2
|
||||
|
||||
### Step 2: Add Memories
|
||||
Review each memory draft from Step 1 and compare it with the retrieved historical memories, then use `add_memory` to manage all memories in one call:
|
||||
|
||||
- For each new memory, fill in the required parameters:
|
||||
* `message_time`: timestamp from the conversation (e.g., '2020-01-01 00:00:00')
|
||||
* `memory_content`: memory content
|
||||
- Add memories when:
|
||||
* The draft contains new information not present in historical memories
|
||||
|
||||
|
||||
**General Guidelines:**
|
||||
- **Skip** drafts if their content is already fully covered by historical memories (avoid redundancy)
|
||||
- You can add memories in a single `add_memory` tool call
|
||||
|
||||
user_message_summary_2: |
|
||||
You are a Profile Agent responsible for managing profiles about {memory_target}.
|
||||
|
||||
## Latest Conversation
|
||||
Format: round<index> [<timestamp>] <role/name>: <content>
|
||||
{context}
|
||||
|
||||
## Current Profiles
|
||||
{profiles}
|
||||
|
||||
## Task
|
||||
Analyze the Latest Conversation and use `update_profiles` to manage profiles (both updates and additions in one call):
|
||||
|
||||
**For profiles_to_update** (updating existing profiles):
|
||||
- For each profile to update, fill in the required parameters:
|
||||
* `profile_id`: ID of the profile to update (from Current Profiles)
|
||||
* `message_time`: timestamp from the conversation (e.g., '2020-01-01 00:00:00')
|
||||
* `profile_key`: profile key or category (e.g., 'name', 'age', 'occupation')
|
||||
* `profile_value`: updated profile value, please be concise. (e.g., 'John Smith')
|
||||
|
||||
**For profiles_to_add** (adding new profiles):
|
||||
- For each new profile, fill in the required parameters:
|
||||
* `message_time`: timestamp from the conversation (e.g., '2020-01-01 00:00:00')
|
||||
* `profile_key`: profile key or category (e.g., 'name', 'age', 'occupation')
|
||||
* `profile_value`: profile value (e.g., 'John Smith')
|
||||
- Add profiles when:
|
||||
* The information represents a new distinct profile not present in Current Profiles
|
||||
* The profile key doesn't exist in Current Profiles
|
||||
* The information cannot be merged into existing profiles
|
||||
|
||||
**General Guidelines:**
|
||||
- Extract all important information comprehensively—do not miss critical details, but avoid any fabrications or unfounded assumptions
|
||||
- You can update and add profiles in a single tool call
|
||||
|
||||
user_message_retrieve: |
|
||||
You are a Memory Retrieval Agent specialized in retrieving {memory_type} memories about {memory_target}.
|
||||
|
||||
## User Profile
|
||||
{user_profile}
|
||||
|
||||
## User Question
|
||||
{context}
|
||||
|
||||
## Multi-Phase Retrieval Strategy
|
||||
Follow these phases sequentially to gather comprehensive information:
|
||||
|
||||
### Phase 1: Semantic Search (No Time Filter)
|
||||
**Tool**: `retrieve_memory` (without time constraints)
|
||||
**Objective**: Cast a wide net to find potentially relevant memories
|
||||
**Approach**:
|
||||
- Execute 3-5 diverse search queries using different formulations:
|
||||
* Original question verbatim
|
||||
* Rephrased variations (different wording, synonyms)
|
||||
* Entity-focused queries (extract and search specific names, places, events)
|
||||
* Keyword-based searches (core concepts, topics)
|
||||
* Related context queries (broader themes)
|
||||
- Review all results before proceeding to next phase
|
||||
|
||||
### Phase 2: Deep Dive into History
|
||||
**Tool**: `read_history`
|
||||
**When to use**: After exhausting retrieval attempts OR when specific conversation context is needed
|
||||
**Important Constraints**:
|
||||
- Each history is very long and resource-intensive to read
|
||||
- **Maximum limit: Read no more than 3 histories total**
|
||||
- Only use this phase when absolutely necessary for answering the question
|
||||
**Approach**:
|
||||
- Extract `history_id` from retrieved memory references
|
||||
- Prioritize the most relevant or recent histories
|
||||
- Can read multiple histories at once by passing multiple history_ids
|
||||
- Be selective: choose only the top 1-3 most promising histories
|
||||
- Use this to understand the full conversation surrounding a memory
|
||||
|
||||
## Response Guidelines
|
||||
- Base your answer EXCLUSIVELY on user profile, retrieved memories, and history data
|
||||
- Never infer, assume, or hallucinate information
|
||||
- Always cite sources with timestamps: `[timestamp] Memory content`
|
||||
- Present conflicting information transparently with respective timestamps
|
||||
- If you find sufficient information to answer the user's question, you may output directly without exhausting all search phases
|
||||
- Exhaust all search strategies before concluding information doesn't exist
|
||||
|
||||
### Output any tangentially related findings, Format:
|
||||
[timestamp] [memory/profile/history] [relevant content1]
|
||||
[timestamp] [memory/profile/history] [relevant content2]
|
||||
|
||||
|
|
@ -1,13 +0,0 @@
|
|||
|
||||
|
||||
# TODO
|
||||
- [] halumem bench开发
|
||||
- [] default版本开发,for cli版本体验
|
||||
- [] cli开发
|
||||
- [] locomo bench开发
|
||||
- [] task memory迁移
|
||||
- [] mcp开发
|
||||
- [] reme外层接口完善
|
||||
- [] reme2 readme完善
|
||||
- [] 看日志,看要这个default版本怎么优化。
|
||||
- [] 学习Clawdbot记忆系统
|
||||
|
|
@ -1,121 +0,0 @@
|
|||
# BFCL
|
||||
Experiment Quick Start Guide
|
||||
|
||||
This guide helps you quickly set up and run BFCL experiments with ReMe integration.
|
||||
|
||||
## Env Setup
|
||||
|
||||
### 1. BFCL installation
|
||||
|
||||
#### clone the repository
|
||||
```bash
|
||||
git clone https://github.com/ShishirPatil/gorilla.git
|
||||
```
|
||||
|
||||
#### Change directory to the `berkeley-function-call-leaderboard`
|
||||
```bash
|
||||
cd gorilla/berkeley-function-call-leaderboard
|
||||
```
|
||||
|
||||
#### Install the package in editable mode
|
||||
```bash
|
||||
conda create -n bfcl-env python==3.12
|
||||
conda activate bfcl-env
|
||||
pip install -e .
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
#### Move the dataset to the data folder under bfcl
|
||||
```bash
|
||||
cp -r bfcl_eval/data {/path/to/bfcl/data}
|
||||
```
|
||||
|
||||
**Note**: The original BFCL data is designed as a benchmark dataset and does not have a train/validation split, you can use ``split_into_trainval.py`` to split JSONL file into train and validation sets.
|
||||
|
||||
### 2. Collect agent trajectories on training data set
|
||||
|
||||
Run the main experiment script to collect agent trajectories on training data set without task memory(`use_memory=False`):
|
||||
|
||||
```bash
|
||||
python run_bfcl.py
|
||||
```
|
||||
|
||||
**Note**:
|
||||
- `max_workers`: Number of parallel workers (default: `4`)
|
||||
- `num_runs`: Number of times each task is repeated (default: `1`)
|
||||
- `model_name`: LLM model name (default: `qwen3-8b`)
|
||||
- `enable_thinking`: Control the model's thinking mode (default: `False`)
|
||||
- `data_path`: Path to the training dataset (default: `./data/multiturn_data_base_train.jsonl`)
|
||||
- `answer_path`: Path to the possible answer, which are used to evaluate the model's output function (default: `./data/possible_answer`)
|
||||
- Results are automatically saved to `./exp_result/{model_name}/{no_think/with_think}` directory
|
||||
|
||||
### 3. Start ReMe Service and Init the task memory pool
|
||||
|
||||
After collecting trajectories, Launch the ReMe service (make sure you have installed ReMe environment, if not please follow the steps in the [ReMe Installation Guide](https://github.com/agentscope-ai/ReMe/blob/main/doc/README.md) to install):
|
||||
|
||||
```bash
|
||||
reme \
|
||||
backend=http \
|
||||
http.port=8002 \
|
||||
llm.default.model_name=qwen-max-2025-01-25 \
|
||||
embedding_model.default.model_name=text-embedding-v4 \
|
||||
vector_store.default.backend=local
|
||||
```
|
||||
|
||||
and then init the task memory pool:
|
||||
|
||||
```bash
|
||||
python init_task_memory_pool.py
|
||||
```
|
||||
|
||||
**Configuration options in `init_task_memory_pool.py`:**
|
||||
- `jsonl_file`: Path to the collloaded trajectories
|
||||
- `service_url`: ReMe service URL (default: `http://localhost:8002`)
|
||||
- `workspace_id`: Workspace ID for the task memory pool (default: `bfcl_test`)
|
||||
- `n_threads`: Number of threads for processing (default: `4`)
|
||||
- `output_file`: Output file to save results (optional)
|
||||
|
||||
Now you have inited the task memory pool using `local` backend (start on `http://localhost:8002`). Then, use `local_file_to_library.py` script to convert the local file to the memory library or run the following `curl` command:
|
||||
```bash
|
||||
curl -X POST "http://0.0.0.0:8002/vector_store" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"workspace_id": "bfcl_test",
|
||||
"action": "dump",
|
||||
"path": "./library"
|
||||
}'
|
||||
```
|
||||
to dump the memory library (default in `./library/bfcl_test.jsonl`).
|
||||
|
||||
Next time, you can import this previously exported task memory data to populate the new started workspace with existing knowledge:
|
||||
```bash
|
||||
curl -X POST "http://0.0.0.0:8002/vector_store" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"workspace_id": "bfcl_test",
|
||||
"action": "load",
|
||||
"path": "./library"
|
||||
}'
|
||||
```
|
||||
|
||||
|
||||
### 4. Run Experiments on Validation Set
|
||||
|
||||
Run you can compare agent performance on the validation set with task memory (`use_memory=True`) and without task memory:
|
||||
|
||||
```bash
|
||||
# remember to change the configuration options, e.g., `data_path=./data/multiturn_data_base_val.jsonl`
|
||||
python run_bfcl.py
|
||||
```
|
||||
|
||||
After running experiments, analyze the statistical results:
|
||||
|
||||
```bash
|
||||
python run_exp_statistic.py
|
||||
```
|
||||
|
||||
**What this script does:**
|
||||
- Processes all result files in `./exp_result/`
|
||||
- Calculates best@k metrics for different k values
|
||||
- Generates a summary table showing performance comparisons
|
||||
- Saves results to `experiment_summary.csv`
|
||||
69
docs/cookbook/faq.md
Normal file
69
docs/cookbook/faq.md
Normal file
|
|
@ -0,0 +1,69 @@
|
|||
# Frequently Asked Questions
|
||||
This document provides answers to frequently asked questions about our paper "[Remember Me, Refine Me: A Dynamic Procedural Memory Framework for Experience-Driven Agent Evolution](https://arxiv.org/pdf/2512.10696)".
|
||||
|
||||
## Reproduction Questions
|
||||
### 1. experimental configuration
|
||||
|
||||
**Example:** Qwen3-8B + AppWorld
|
||||
**Launch the ReMe service:**
|
||||
```bash
|
||||
reme2 \
|
||||
backend=http \
|
||||
http.port=8002 \
|
||||
llms.default.model_name=qwen3-8b \
|
||||
embedding_models.default.model_name=text-embedding-v4 \
|
||||
vector_stores.default.backend=es \
|
||||
vector_stores.default.hosts=http://xx.yy.zz.mm:nn
|
||||
```
|
||||
**Evaluation Code:** [run_appworld.py](https://github.com/agentscope-ai/ReMe/blob/main/benchmark/appworld/run_appworld.py) with the following parameters
|
||||
|Experimental Settings|No Memory |ReMe (fixed) |ReMe (dynamic)|
|
||||
|---|---|---|---|
|
||||
|max_workers|16|16|16|
|
||||
|batch_size|8|8|8|
|
||||
|num_runs|4|4|1|
|
||||
|num_trials|1|1|3|
|
||||
|model_name|"qwen3-8b"|"qwen3-8b"|"qwen3-8b"|
|
||||
|use_memory| False| True|True|
|
||||
|use_memory_addition|False|False|True|
|
||||
|use_memory_deletion|False|False|True|
|
||||
|memory_base_url|""|"http://0.0.0.0:8002/"|"http://0.0.0.0:8002/"|
|
||||
|load_file_path|""|[appworld_qwen3_8b.jsonl](https://github.com/agentscope-ai/ReMe/tree/main/docs/library/paper_data/task/appworld_qwen3_8b.jsonl)|[appworld_qwen3_8b.jsonl](https://github.com/agentscope-ai/ReMe/tree/main/docs/library/paper_data/task/appworld_qwen3_8b.jsonl)|
|
||||
|
||||
For parameter meanings, you can refer to [docs/cookbook/appworld](https://github.com/zouyingcao/ReMe/blob/main/docs/cookbook/appworld/quickstart.md) .
|
||||
|
||||
> [!NOTE]
|
||||
> - Qwen3 thinking mode is activated for BFCL-V3 tasks and disabled for AppWorld tasks.
|
||||
> - In ReMe(fixed) setting, there is no need to restart the ReMe service at each run since the experience pool is fixed. However, in ReMe(dynamic) setting, we need run separately to ensure consistent initial state. That is to say, to calculate Pass@4, you need 4 independent runs with restarting ReMe service and setting `num_runs=1` in each run.
|
||||
|
||||
### 2. about experience pool initialization
|
||||
Taking Appworld as an example, you can refer to issues [#55](https://github.com/agentscope-ai/ReMe/issues/55), [#58](https://github.com/agentscope-ai/ReMe/issues/58). To reproduce the results in our paper, you can use our constructed memory data in [docs/library/paper_data](https://github.com/agentscope-ai/ReMe/tree/main/docs/library/paper_data/task).
|
||||
|
||||
### 3. evaluation metrics
|
||||
- In our AppWorld experiments, we report Task Goal Completion (TGC) metric (claimed in Appendix A of our [paper](https://arxiv.org/pdf/2512.10696)), which measures percentage of tasks for which the agent passes all evaluation tests. [`after_score`](https://github.com/agentscope-ai/ReMe/blob/main/benchmark/appworld/appworld_react_agent.py#L218) is the percentage of tests passed for per task. To calculate TGC, only `after_score=1` means task completion. Therefore, we use threshold=1 in [run_exp_statistic.py](https://github.com/agentscope-ai/ReMe/blob/main/benchmark/appworld/run_exp_statistic.py#L43) to get Pass@k.
|
||||
- In our paper, `Avg@4` is the `Pass@1` performance averaged over 4 independent runs. For simplicity, we organize the total collected 4 trajectories in a single file to calculate Pass@1 and Pass@4 together. Then, the results of Pass@1 and Avg@4 are equivalent.
|
||||
|
||||
|
||||
### 4. reproduce baselines
|
||||
- For Qwen3-series No-Memory performance on AppWorld, you can refer to issue [#49](https://github.com/agentscope-ai/ReMe/issues/49).
|
||||
- About A-mem and LangMem code, please see [#67](https://github.com/agentscope-ai/ReMe/issues/67).
|
||||
|
||||
## Environment Setup
|
||||
### 1. BFCL-V3 code version
|
||||
We use the BFCL GitHub repository with commit_id=[ea13468](https://github.com/ShishirPatil/gorilla/commit/ea13468e4423454d0c213704fb87cf7cb3990433) in our experiments.
|
||||
|
||||
### 2. preprocess BFCL-V3 multi_turn_base data
|
||||
Before running the experiments, you need to preprocess the BFCL-V3 data using this [script](https://github.com/agentscope-ai/ReMe/blob/main/benchmark/bfcl/preprocess.py) to get the suitable data format. Then, we randomly split the multi-turn-base data into train (50) and test (150) sets using [split_into_trainval.py](https://github.com/agentscope-ai/ReMe/blob/main/benchmark/bfcl/split_into_trainval.py) (our used split is [here](https://github.com/agentscope-ai/ReMe/issues/45#issuecomment-3890215360)). The training set is used to construct the initial experience pool and the remaining 150 testing tasks serve as the evaluation set.
|
||||
|
||||
### 3. pydantic version issue when running Appworld
|
||||
AppWorld depends on an older version of pydantic, which is why a separate environment is needed. If you encounter issues running the experiments, try `pip install appworld` to override the dependencies.
|
||||
|
||||
### 4. AppWorld data not found
|
||||
Ensure `appworld download data` completed successfully.
|
||||
|
||||
## Technical Questions
|
||||
### 1. about memory growth
|
||||
See [#44](https://github.com/agentscope-ai/ReMe/issues/44).
|
||||
### 2. code for Experience Refinement
|
||||
See [#52](https://github.com/agentscope-ai/ReMe/issues/52).
|
||||
### 3. context length issue with AppWorld
|
||||
See [#81](https://github.com/agentscope-ai/ReMe/issues/81).
|
||||
|
|
@ -1,13 +0,0 @@
|
|||
from loguru import logger
|
||||
|
||||
用英文注释,完善module/class/function docstring,要一句话简洁,不要变更代码逻辑,符合pep和pylint规范,使用list而不是typing.List/Dict,不使用typing.Union
|
||||
|
||||
看看代码有什么问题
|
||||
用英文注释,完善module/class/function docstring,要一句话简洁,代码要简洁,符合pep和pylint规范,使用list而不是typing.List,不使用typing.Union
|
||||
C0114: Missing module docstring (missing-module-docstring)
|
||||
C0115: Missing class docstring (missing-class-docstring)
|
||||
C0116: Missing function or method docstring (missing-function-docstring)
|
||||
done: { for f in ./*.py; do [[ "$f" != "./__init__.py" ]] && grep -v '^[[:space:]]*#' "$f"; done; } | pbcopy
|
||||
|
||||
然后是一个完整的tests,但是不要用其他的包,只是test开头的函数或者类,要求from loguru import logger
|
||||
写一个测试文件,不要使用pytest,普通的test,要求英文注释
|
||||
|
|
@ -1,18 +0,0 @@
|
|||
# Future Work
|
||||
|
||||
- [ ] P0 ReMe documentation style migration: Recommend using the same doc and jupyter structure as Agentscope Runtime @jiaji
|
||||
- [ ] P0 ReMe integration with agentscope Personal/Task/Tool @jinli
|
||||
- [ ] P0 ReMe sample library examples [show case](https://github.com/agentscope-ai/agentscope-samples/tree/main/functionality/long_term_memory_mem0) @jinli
|
||||
- [ ] P0 Decouple flowllm dependencies @jinli
|
||||
- [ ] P0 ReMe support for import, improve code documentation @jinli
|
||||
- [ ] P1 ReMe integration with asio tool_memory @jinli
|
||||
- [ ] P2 ReMe integration with agentscope-Runtime tool_memory @jinli
|
||||
|
||||
- [ ] P0 Task Memory Research Paper @zhoyin
|
||||
|
||||
- [ ] P1 Context interface definition @jinli
|
||||
|
||||
- [ ] P2 Database layer interface unification @jinli
|
||||
- [ ] P2 Automatic Tool Exploration Mode @wangcan
|
||||
- [ ] P2 Mem-Agent Exploration @weikang
|
||||
- [ ] P2 Desktop Pet Personal Assistant
|
||||
|
|
@ -1,735 +0,0 @@
|
|||
# ReMeV2 深度设计文档:渐进式 Agentic Memory 方案
|
||||
|
||||
## 一、 背景与现状分析
|
||||
|
||||
### 1.1 当前面临的挑战
|
||||
|
||||
* **外功修炼(接口易用性)**:现有的 `server-client` 模式对新手开发者不够友好,集成成本高,需要更直观、纯 Pythonic 的调用方式。
|
||||
* **内功修炼(架构深度)**:受 `skills` 和 `agentic memory` 启发,现有的存储检索较为机械。我们需要一种基于**渐进式检索(Progressive Retrieval)**与**渐进式总结(Progressive Summarization)**的智能体记忆方案。
|
||||
|
||||
### 1.2 核心目标
|
||||
|
||||
1. **极简开发体验**:开发者友好,全异步接口,支持本地直接运行与 CLI 体验。
|
||||
2. **认知架构升级**:引入 渐进式检索 & 渐进式总结 的 Agentic 模式,融合多种记忆,让记忆的存取具备“思考”过程。
|
||||
3. **生态融合**:原生支持 AgentScope、LangChain 等主流框架。
|
||||
|
||||
---
|
||||
|
||||
## 二、 竞品调研与启示
|
||||
|
||||
### 2.1 主流竞品深度对比
|
||||
|
||||
| 产品 | 设计哲学 | 核心优势 | 局限性 |
|
||||
|-------------|----------|---------------------------------------------|-------------------|
|
||||
| **mem0** | 智能便签本 | 原子事实提取,极高 Token 效率。 | 缺乏对复杂逻辑链条的支持。 |
|
||||
| **Letta** | 带硬盘的 CPU | 模拟计算机三级存储(Core/Recall/Archival),Agent 自主控存。 | 状态机管理相对复杂。 |
|
||||
| **MIRIX** | 认知架构图谱 | 实体-关系双引擎,支持记忆“进化”与“固化”。 | 侧重研究,落地集成门槛较高。 |
|
||||
| **LangMem** | 用户档案系统 | 异步 Compaction(压缩),Schema 驱动,强一致性。 | 偏向 SaaS 应用,灵活性略逊。 |
|
||||
|
||||
### 2.2 mem0
|
||||
- https://github.com/mem0ai/mem0
|
||||
- https://docs.mem0.ai/core-concepts/memory-operations/add
|
||||
- https://docs.mem0.ai/core-concepts/memory-operations/search
|
||||
- https://docs.mem0.ai/core-concepts/memory-operations/update
|
||||
- https://docs.mem0.ai/core-concepts/memory-operations/delete
|
||||
|
||||
#### 2.2.1 API Reference
|
||||
| 接口名称 | 核心输入参数 (Inputs) | 核心输出 (Outputs) | 背后逻辑 (Internal Logic) |
|
||||
| --- | --- | --- | --- |
|
||||
| **Add** | `messages` (文本/对话), `user_id`, `metadata` | `id`, `event` (ADD/UPDATE), `data` | **提取与合并**:LLM 提取事实,自动去重并更新已有记忆,而非简单堆叠。 |
|
||||
| **Search** | `query` (自然语言), `filters`, `limit` | `id`, `memory` (事实文本), `score`, `metadata` | **语义检索**:基于向量相似度查找最相关的“原子事实”,支持多维过滤。 |
|
||||
| **Update** | `memory_id` (必填), `data` (新内容) | 操作状态 (Success/Fail) | **手动干预**:允许开发者对特定的事实进行精确修正。 |
|
||||
| **Delete** | `memory_id` 或 `user_id` (清空) | 操作状态 (Success/Fail) | **遗忘机制**:物理删除或逻辑移除不再需要的信息。 |
|
||||
|
||||
#### 2.2.2 Tech Strategy & Benefits
|
||||
| 维度 | 技术方案 (Technical Solution) | 核心优势 (Key Advantages) |
|
||||
| --- | --- | --- |
|
||||
| **存储架构** | **混合存储**:向量数据库 (Vector) + 图数据库 (Graph) + 关系型元数据。 | **多维关联**:不仅能搜到相似内容,还能理解实体间的逻辑关系(如“父子”、“因果”)。 |
|
||||
| **数据处理** | **原子化事实提取**:利用 LLM 将长篇对话压缩为简短的 Fact。 | **极高 Token 效率**:注入 Prompt 的内容更精炼,减少 90% 以上的冗余信息,大幅降本。 |
|
||||
| **管理层级** | **多级联动**:User (长期) Agent (专业) Session (短期)。 | **个性化定制**:实现跨会话的“长效记忆”,AI 能记住用户一个月前说过的偏好。 |
|
||||
| **冲突处理** | **自适应更新算法**:新信息进入时自动比对旧记忆。 | **数据一致性**:自动处理矛盾信息(如用户更换了住址),确保记忆库始终是“最新真理”。 |
|
||||
| **兼容性** | **解耦设计**:支持多种 Embedding 模型与向量数据库后端。 | **快速集成**:几行代码即可为现有 LLM 应用增加记忆层,适配各种生产环境。 |
|
||||
|
||||
|
||||
---
|
||||
|
||||
### 2.3 Letta
|
||||
- https://github.com/letta-ai/letta
|
||||
- https://docs.letta.com/guides/agents/archival-memory/
|
||||
- https://docs.letta.com/guides/agents/archival-search/
|
||||
|
||||
#### 2.3.1 存储架构层级 (Memory Tiering)
|
||||
|
||||
Letta 将记忆分为三个物理/逻辑层,模拟计算机的存储架构:
|
||||
|
||||
| 记忆层级 | 存储介质 | 访问方式 | 核心作用 |
|
||||
| --- | --- | --- | --- |
|
||||
| **Core Memory** | **上下文窗口 (Prompt)** | 直接读写 | **即时意识**:包含 `Persona`(AI 设定)和 `Human`(用户信息)。Agent 随时可见,响应最快。 |
|
||||
| **Recall Memory** | **关系型数据库 (SQL)** | 分页检索 | **短期/历史回顾**:存储完整的对话流(Messages)。用于回答“你刚才说了什么”。 |
|
||||
| **Archival Memory** | **向量数据库 (Vector)** | 语义搜索 | **长期知识库**:存储海量事实或文档。Agent 通过工具自主检索或存入。 |
|
||||
|
||||
#### 2.3.2 核心操作接口 (API & Tool Reference)
|
||||
|
||||
在 Letta 中,记忆的操作通常封装为 **Tools**,由 Agent 根据推理需求主动调用。
|
||||
|
||||
| 接口/工具名称 | 输入参数 (Inputs) | 核心输出 (Outputs) | 背后逻辑 (Internal Logic) |
|
||||
| --- | --- | --- | --- |
|
||||
| **`core_memory_update`** | `section`, `new_content` | 更新后的段落内容 | **原子替换**:直接修改 System Prompt 中的特定块(如:更新用户的职业或 AI 的性格偏好)。 |
|
||||
| **`archival_memory_insert`** | `content` (字符串) | 写入状态/ID | **知识沉淀**:将当前对话中的重要信息或外部文件片段“持久化”到向量数据库。 |
|
||||
| **`archival_memory_search`** | `query`, `page` | 匹配的文本块列表 | **主动 RAG**:Agent 意识到知识不足时,自主发起向量检索,并将结果拉入临时上下文。 |
|
||||
| **`conversation_search`** | `query`, `start_date` | 历史消息记录 | **全文检索**:在 Recall Memory 中根据关键词或时间戳查找历史对话详情。 |
|
||||
| **`send_message`** | `message`, `agent_id` | 响应流/状态更新 | **状态循环**:这是主入口,触发 Agent 的“思考-行动-观察”循环,自动处理内存同步。 |
|
||||
|
||||
#### 2.3.3 技术策略与核心优势 (Tech Strategy & Benefits)
|
||||
|
||||
| 维度 | 技术方案 (Technical Solution) | 核心优势 (Key Advantages) |
|
||||
| --- | --- | --- |
|
||||
| **状态持久化** | **Agent State Snapshot**:将 Agent 的所有内存、工具定义和历史记录打包存入数据库。 | **无限存续**:Agent 不再是无状态的 API 调用。重启服务器后,Agent 依然记得所有细节。 |
|
||||
| **自主演进** | **Self-Editing Loop**:Agent 拥有修改自己 Core Memory 的权限(通过函数调用)。 | **认知闭环**:AI 能在交流中发现矛盾并自我更正,例如发现用户搬家后自动更新 `Human` 模块。 |
|
||||
| **算力调度** | **OOC (Out-of-Context) 管理**:当对话过长,系统自动将旧消息从 Core 移入 Recall。 | **突破 Context 限制**:在 8k 窗口的模型上也能处理相当于 1M 窗口的逻辑量,且成本更低。 |
|
||||
| **多代理协同** | **Letta Server 中控**:统一管理多个 Agent 的状态机与资源访问权限。 | **企业级扩展**:支持创建 Agent 团队,每个 Agent 拥有独立的记忆空间但可共享 Archival 库。 |
|
||||
| **解耦灵活性** | **Provider Agnostic**:后端支持 Postgres/Chroma,前端支持 OpenAI/Anthropic/Local LLMs。 | **无缝迁移**:不绑定特定模型,开发者可以根据成本或能力随时更换底座。 |
|
||||
|
||||
#### 2.3.4 与 mem0 的深度对比
|
||||
|
||||
* **设计哲学**:
|
||||
* **mem0** 像是一个**“智能记事本”**,它在后台默默地帮你总结事实。
|
||||
* **Letta** 像是一个**“带硬盘的 CPU”**,它把记忆管理完全交给了 Agent 自己的逻辑推理。
|
||||
|
||||
|
||||
* **交互模式**:
|
||||
* **mem0** 通常是外部干预(Add/Search)。
|
||||
* **Letta** 强调 **Agentic Control**(Agent 意识到需要搜索时才去搜索),这种模式更接近人类的思维过程。
|
||||
|
||||
---
|
||||
|
||||
### 2.4 MIRIX
|
||||
- https://github.com/Mirix-AI/MIRIX
|
||||
- https://docs.mirix.io/
|
||||
|
||||
#### 2.4.1 API Reference
|
||||
|
||||
| 接口名称 | 核心输入参数 (Inputs) | 核心输出 (Outputs) | 背后逻辑 (Internal Logic) |
|
||||
| --- | --- | --- | --- |
|
||||
| **Add** | `content` (观察/对话), `agent_id`, `context_type` (如任务/闲聊) | `memory_id`, `graph_nodes`, `status` | **实体建模**:不只是提取事实,而是将信息拆解为实体(Entities)与关系(Relations),并挂载到智能体的知识图谱中。 |
|
||||
| **Query** | `query` (意图), `scope` (全局/局部), `top_k` | `retrieved_memories`, `relation_paths`, `score` | **混合检索**:结合向量(Vector)的语义相关性和图(Graph)的拓扑连接性,寻找具有逻辑深度背景的记忆。 |
|
||||
| **Evolve** | `target_memories` (可选), `agent_id` | `optimized_structure`, `merged_nodes` | **记忆固化/压缩**:模仿人类大脑的“睡眠”机制,自动合并碎片化记忆,将短期经验转化为长期的结构化知识。 |
|
||||
| **Observe** | `interaction_stream`, `feedback` | `insights`, `priority_update` | **实时学习**:根据用户反馈或环境变化,动态调整记忆的权重(Importance)和置信度。 |
|
||||
|
||||
#### 2.4.2 Tech Strategy & Benefits
|
||||
|
||||
| 维度 | 技术方案 (Technical Solution) | 核心优势 (Key Advantages) |
|
||||
| --- | --- | --- |
|
||||
| **存储架构** | **语义-关系双引擎**:向量索引(Vector Index)+ 属性图(Property Graph)。 | **深度上下文**:不仅知道“是什么”,还能通过图路径推理出“为什么”,有效解决 LLM 幻觉问题。 |
|
||||
| **记忆层级** | **三层架构**:感知记忆 (Perception) -> 语义记忆 (Semantic) -> 经验记忆 (Episodic)。 | **任务适应性**:不同任务自动匹配不同的记忆深度,短期任务关注细节,长期任务关注模式。 |
|
||||
| **演化机制** | **自主固化 (Self-Consolidation)**:通过 LLM 定期对冗余、矛盾信息进行清洗和逻辑抽象。 | **永久生命力**:解决随时间推移记忆库膨胀导致的检索噪声,确保记忆库“越用越聪明”。 |
|
||||
| **推理增强** | **基于记忆的 RAG+**:在检索到的事实基础上,额外提供关联的逻辑链条(Logic Chains)。 | **辅助决策**:为 Agent 提供决策支撑,使其在处理复杂流程时具备类似“长期经验值”的直觉。 |
|
||||
| **多代理协同** | **内存共享协议**:支持 Agent 之间的记忆交换与知识同步。 | **群体智能**:多个 Agent 可以共享同一套底层知识体系,同时保留各自的私有工作记忆。 |
|
||||
|
||||
#### 2.4.3 与 mem0 的主要区别
|
||||
|
||||
* **Mem0** 侧重于**个性化偏好存储**(Personalization),核心是记住“用户喜欢什么”。
|
||||
* **MIRIX** 侧重于**智能体认知架构**(Agent Cognition),核心是让 Agent 具备类似人类的“知识归纳”和“逻辑推理”记忆能力。
|
||||
|
||||
---
|
||||
|
||||
### 2.5 LangMem
|
||||
- https://github.com/langchain-ai/langmem
|
||||
- https://langchain-ai.github.io/langmem/
|
||||
|
||||
#### 2.5.1 API Reference
|
||||
|
||||
| 接口名称 | 核心输入参数 (Inputs) | 核心输出 (Outputs) | 背后逻辑 (Internal Logic) |
|
||||
| --- | --- | --- | --- |
|
||||
| **Add Messages** | `thread_id`, `messages` (List), `user_id` | 操作确认 / 任务 ID | **流式注入**:将原始对话追加到指定的 Thread。LangMem 会自动关联用户上下文,准备进行后续的异步处理。 |
|
||||
| **Query Memory** | `user_id`, `query` (语义描述), `namespace` | 结构化记忆对象 (JSON / Text) | **多维检索**:不仅支持向量相似度搜索,还能根据定义的 Schema 返回结构化的用户画像或知识状态。 |
|
||||
| **Trigger Logic** | `thread_id`, `memory_type` | 更新后的 Memory State | **异步固化**:后台启动 LLM 任务,将长篇对话“压缩”并“提取”到长期存储中。支持自定义提取逻辑(如更新用户信息)。 |
|
||||
| **Manage State** | `user_id`, `patch_data` (增量更新) | 成功/失败 状态 | **精确受控**:开发者可以直接修改持久化的状态(State),支持类似于 Git 的状态管理。 |
|
||||
|
||||
#### 2.5.2 Tech Strategy & Benefits
|
||||
|
||||
| 维度 | 技术方案 (Technical Solution) | 核心优势 (Key Advantages) |
|
||||
| --- | --- | --- |
|
||||
| **存储架构** | **Stateful Persistence**:基于关系型数据库 (Postgres) + 向量索引。 | **强一致性**:利用数据库事务确保记忆更新的可靠性,支持复杂的结构化查询与过滤。 |
|
||||
| **数据处理** | **异步化 Compaction (压缩)**:在对话间隙通过后台 Worker 提取知识。 | **无感延迟**:核心对话流程不被记忆提取阻塞,通过定时或事件驱动完成“记忆固化”,优化用户体验。 |
|
||||
| **管理层级** | **Thread -> User -> Organization**:三层级联记忆。 | **上下文隔离**:完美适配 SaaS 应用场景,既能记住单次对话(Thread),也能沉淀用户习惯(User)。 |
|
||||
| **逻辑引擎** | **Schema-Driven (模式驱动)**:允许定义 JSON Schema 来规范记忆内容。 | **高度可预测**:输出不再是散乱的句子,而是结构化的字段,方便下游程序直接调用逻辑(如自动填充表单)。 |
|
||||
| **集成生态** | **LangGraph 原生集成**:作为 Checkpointer 或存储节点直接接入。 | **生态协同**:如果你已经在用 LangChain,LangMem 可以无缝接管状态流转,无需重写底层存储逻辑。 |
|
||||
|
||||
#### 2.5.3 与 mem0 的核心差异
|
||||
|
||||
* **mem0** 像是一个**“便签本”**:它擅长从每一句话里抠出零散的事实(如“我喜欢吃苹果”),然后把它们存成一条条语义片段。
|
||||
* **LangMem** 像是一个**“用户档案系统”**:它更擅长分析一整段对话,然后更新一个复杂的 JSON 档案(如更新用户的偏好模型、性格标签、历史任务状态)。
|
||||
|
||||
---
|
||||
|
||||
## 三、 ReMeV2 API 接口设计
|
||||
|
||||
### 3.1 Long-Term Memory (长期记忆)
|
||||
|
||||
#### 3.1.1 Basic Usage (基础用法)
|
||||
|
||||
The most straightforward way to use ReMe for long-term memory management. Supports basic summary and retrieval operations.
|
||||
|
||||
```python
|
||||
import os
|
||||
from reme_ai import ReMe
|
||||
|
||||
os.environ["REME_LLM_API_KEY"] = "sk-..."
|
||||
os.environ["REME_LLM_BASE_URL"] = "https://dashscope.aliyuncs.com/compatible-mode/v1"
|
||||
os.environ["REME_EMBEDDING_API_KEY"] = "sk-..."
|
||||
os.environ["REME_EMBEDDING_BASE_URL"] = "https://dashscope.aliyuncs.com/compatible-mode/v1"
|
||||
|
||||
memory = ReMe(
|
||||
memory_space="remy", # workspace identifier
|
||||
llm={"backend": "openai", "model": "qwen-plus", "temperature": 0.6},
|
||||
embedding={"backend": "openai", "model": "text-embedding-v4", "dimension": 1024},
|
||||
vector_store={"backend": "local_file"}, # supported: local_file, chromadb, qdrant, etc.
|
||||
)
|
||||
|
||||
# Summarize conversation into memory
|
||||
result = await memory.summary(
|
||||
messages=[
|
||||
{"role": "user", "content": "I'm travelling to SF"},
|
||||
{"role": "assistant", "content": "That's great to hear!"}
|
||||
],
|
||||
user_id="Alice",
|
||||
# memory_type="auto" # default: auto (auto, personal, procedural, tool)
|
||||
)
|
||||
|
||||
# Retrieve relevant memories
|
||||
memories = await memory.retrieve(
|
||||
query="what is your travel plan?",
|
||||
limit=3,
|
||||
user_id="Alice",
|
||||
# memory_type="auto" # default: auto
|
||||
)
|
||||
memories_str = "\n".join(f"- {m['memory']}" for m in memories["results"])
|
||||
print(memories_str)
|
||||
```
|
||||
|
||||
#### 3.1.2 CLI Chat Application (命令行聊天应用)
|
||||
|
||||
A complete example demonstrating how to build a memory-enhanced chatbot with CLI interface.
|
||||
|
||||
```python
|
||||
import os
|
||||
from reme_ai import ReMe
|
||||
from openai import OpenAI
|
||||
|
||||
os.environ["REME_LLM_API_KEY"] = "sk-..."
|
||||
os.environ["REME_LLM_BASE_URL"] = "https://dashscope.aliyuncs.com/compatible-mode/v1"
|
||||
os.environ["REME_EMBEDDING_API_KEY"] = "sk-..."
|
||||
os.environ["REME_EMBEDDING_BASE_URL"] = "https://dashscope.aliyuncs.com/compatible-mode/v1"
|
||||
|
||||
memory = ReMe(
|
||||
memory_space="remy",
|
||||
llm={"backend": "openai", "model": "qwen-plus", "temperature": 0.6},
|
||||
embedding={"backend": "openai", "model": "text-embedding-v4", "dimension": 1024},
|
||||
vector_store={"backend": "local_file"},
|
||||
)
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "sk-..."
|
||||
os.environ["OPENAI_BASE_URL"] = "https://dashscope.aliyuncs.com/compatible-mode/v1"
|
||||
openai_client = OpenAI()
|
||||
|
||||
def chat_with_memories(
|
||||
query: str,
|
||||
history_messages: list[dict],
|
||||
user_name: str = "",
|
||||
start_summary_size: int = 2,
|
||||
keep_size: int = 0
|
||||
) -> str:
|
||||
# Retrieve relevant memories for the query
|
||||
memories = memory.retrieve(query=query, user_id=user_name, limit=3)
|
||||
|
||||
# Build system prompt with memories
|
||||
system_prompt = (
|
||||
"You are a helpful AI named `Remy`. Use the user memories to answer the question. "
|
||||
"If you don't know the answer, just say you don't know. Don't try to make up an answer.\n"
|
||||
)
|
||||
if memories:
|
||||
memories_str = "\n".join(f"- {m['memory']}" for m in memories["results"])
|
||||
system_prompt += f"User Memories:\n{memories_str}\n"
|
||||
|
||||
# Generate response
|
||||
system_message = {"role": "system", "content": system_prompt}
|
||||
history_messages.append({"role": "user", "content": query})
|
||||
response = openai_client.chat.completions.create(
|
||||
model="qwen-plus",
|
||||
messages=[system_message] + history_messages
|
||||
)
|
||||
history_messages.append({"role": "assistant", "content": response.choices[0].message.content})
|
||||
|
||||
# Summarize history when it gets too long
|
||||
if len(history_messages) >= start_summary_size:
|
||||
memory.summary(history_messages[:-keep_size], user_id=user_name)
|
||||
print("Current memories: " + memory.list_memories(user_id=user_name))
|
||||
history_messages = history_messages[-keep_size:]
|
||||
|
||||
return history_messages[-1]["content"]
|
||||
|
||||
def main():
|
||||
user_name = input("Enter your name: ").strip()
|
||||
print("Chat with Remy (type 'exit' to quit)")
|
||||
|
||||
messages = []
|
||||
while True:
|
||||
user_input = input(f"{user_name}: ").strip()
|
||||
if user_input.lower() == 'exit':
|
||||
print("Goodbye!")
|
||||
break
|
||||
|
||||
print(f"Remy: {chat_with_memories(user_input, messages, user_name)}")
|
||||
|
||||
# Cleanup
|
||||
memory.delete_all_memories(user_id=user_name)
|
||||
print("All memories deleted")
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
```
|
||||
|
||||
#### 3.1.3 Advanced Usage (高级用法)
|
||||
|
||||
For advanced users who want to customize retriever and summarizer behavior with Agentic mode.
|
||||
|
||||
```python
|
||||
import os
|
||||
from reme_ai import ReMe
|
||||
from reme_ai.retriever import AgenticRetriever
|
||||
from reme_ai.summarizer import AgenticSummarizer
|
||||
from reme_ai.tools import ATool, BTool, CTool
|
||||
|
||||
os.environ["REME_LLM_API_KEY"] = "sk-..."
|
||||
os.environ["REME_LLM_BASE_URL"] = "https://dashscope.aliyuncs.com/compatible-mode/v1"
|
||||
os.environ["REME_EMBEDDING_API_KEY"] = "sk-..."
|
||||
os.environ["REME_EMBEDDING_BASE_URL"] = "https://dashscope.aliyuncs.com/compatible-mode/v1"
|
||||
|
||||
memory = ReMe(
|
||||
memory_space="remy",
|
||||
llm={"backend": "openai", "model": "qwen-plus", "temperature": 0.6},
|
||||
embedding={"backend": "openai", "model": "text-embedding-v4", "dimension": 1024},
|
||||
vector_store={"backend": "local_file"},
|
||||
use_agentic_mode=True,
|
||||
)
|
||||
|
||||
# Customize retriever and summarizer with custom tools and prompts
|
||||
memory.set_retriever(
|
||||
AgenticRetriever(tools=[ATool(), BTool(), CTool()]),
|
||||
system_prompt="Custom retrieval instructions..."
|
||||
)
|
||||
memory.set_summarizer(
|
||||
AgenticSummarizer(tools=[ATool(), BTool(), CTool()])
|
||||
)
|
||||
|
||||
# Use the customized memory system
|
||||
result = memory.summary(
|
||||
messages=[
|
||||
{"role": "user", "content": "I'm travelling to SF"},
|
||||
{"role": "assistant", "content": "That's great to hear!"}
|
||||
],
|
||||
user_id="Alice",
|
||||
memory_type="auto", # auto, personal, procedural, tool
|
||||
)
|
||||
|
||||
memories = memory.retrieve(
|
||||
query="what is your travel plan?",
|
||||
limit=3,
|
||||
user_id="Alice",
|
||||
memory_type="auto",
|
||||
)
|
||||
memories_str = "\n".join(f"- {m['memory']}" for m in memories["results"])
|
||||
print(memories_str)
|
||||
```
|
||||
|
||||
### 3.2 Short-Term Memory (短期记忆)
|
||||
|
||||
#### 3.2.1 Basic Usage (基础用法)
|
||||
|
||||
Context offload/reload API for managing short-term conversational memory within a session.
|
||||
|
||||
```python
|
||||
import os
|
||||
from reme_ai import ReMe
|
||||
|
||||
os.environ["REME_LLM_API_KEY"] = "sk-..."
|
||||
os.environ["REME_LLM_BASE_URL"] = "https://dashscope.aliyuncs.com/compatible-mode/v1"
|
||||
os.environ["REME_EMBEDDING_API_KEY"] = "sk-..."
|
||||
os.environ["REME_EMBEDDING_BASE_URL"] = "https://dashscope.aliyuncs.com/compatible-mode/v1"
|
||||
|
||||
memory = ReMe(
|
||||
memory_space="remy",
|
||||
llm={"backend": "openai", "model": "qwen-plus", "temperature": 0.6},
|
||||
embedding={"backend": "openai", "model": "text-embedding-v4", "dimension": 1024},
|
||||
vector_store={"backend": "local_file"},
|
||||
)
|
||||
|
||||
# Offload context when conversation gets too long
|
||||
result = memory.offload_context(
|
||||
messages=[
|
||||
{"role": "user", "content": "I'm travelling to SF"},
|
||||
{"role": "assistant", "content": "That's great to hear!"}
|
||||
],
|
||||
)
|
||||
|
||||
# Reload relevant context when needed
|
||||
memories = memory.reload_context(
|
||||
query="what is your travel plan?",
|
||||
limit=3,
|
||||
)
|
||||
memories_str = "\n".join(f"- {m['memory']}" for m in memories["results"])
|
||||
print(memories_str)
|
||||
```
|
||||
|
||||
### 3.3 Framework Integration (框架集成)
|
||||
|
||||
#### 3.3.1 Integration with AgentScope
|
||||
|
||||
Integration example for AgentScope ReActAgent with long-term memory support.
|
||||
|
||||
```python
|
||||
# TODO: Provide AgentScope integration example
|
||||
```
|
||||
|
||||
#### 3.3.2 Integration with LangChain
|
||||
|
||||
Integration example for LangChain agents with ReMe memory layer.
|
||||
|
||||
```python
|
||||
# TODO: Provide LangChain integration example
|
||||
```
|
||||
|
||||
### 3.4 OpenAI Compatible Interface
|
||||
|
||||
OpenAI-compatible API interface for seamless integration with existing OpenAI-based applications.
|
||||
|
||||
```python
|
||||
# TODO: Research and implement OpenAI-compatible interface
|
||||
# - Support for threads and assistants API
|
||||
# - Compatible with OpenAI SDK
|
||||
# - Support for streaming responses
|
||||
```
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## 四、核心方案设计
|
||||
|
||||
### 4.1 设计概述
|
||||
|
||||
ReMeV2 采用简洁的架构设计,核心理念为:**ReMeV2 = Tool(s) + Agent(s)**
|
||||
|
||||
- **Tool层**:提供原子化的记忆操作能力,包括增删改查、检索、元数据管理等基础操作
|
||||
- **Agent层**:基于Tool层构建的智能代理,负责复杂的记忆管理逻辑,如分类总结、渐进式检索等
|
||||
- **Runtime层**:内部调度机制,协调Tool和Agent的交互流程
|
||||
|
||||
### 4.2 Tool层设计
|
||||
|
||||
Tool层提供装饰器形式的记忆操作工具,每个工具类通过 `@tool` 装饰器注册,明确定义初始化参数和调用参数。
|
||||
|
||||
#### 4.2.1 基类:BaseMemoryToolOp
|
||||
|
||||
**初始化参数:**
|
||||
- `enable_multiple` (bool): Enable multi-item operation mode. Default: `True`
|
||||
- `enable_thinking_params` (bool): Include thinking parameter in tool schema for model reasoning. Default: `False`
|
||||
- `memory_metadata_dir` (str): Directory path for storing memory metadata. Default: `"./memory_metadata"`
|
||||
|
||||
#### 4.2.2 Tool操作列表
|
||||
|
||||
以下是所有Tool操作的完整定义,包括继承关系、初始化参数和调用参数:
|
||||
|
||||
| Tool类 | 继承自 | 初始化参数(除基类外) | Tool Call参数(单项模式) | Tool Call参数(多项模式) |
|
||||
|----------------------------|------------------|------------------------------------------------------------------------------------------------------------------|-----------------------------------------------------------------------------------------------------------------|-----------------------------------------------------------------------------------------------------------------------|
|
||||
| **AddMemoryOp** | BaseMemoryToolOp | `add_when_to_use` (bool, 默认: False)<br>`add_metadata` (bool, 默认: True) | `when_to_use` (str, 可选)<br>`memory_content` (str, 必需)<br>`metadata` (dict, 可选) | `memories` (array, 必需):<br> - `when_to_use` (str, 可选)<br> - `memory_content` (str, 必需)<br> - `metadata` (dict, 可选) |
|
||||
| **UpdateMemoryOp** | BaseMemoryToolOp | 无 | `memory_id` (str, 必需)<br>`memory_content` (str, 必需)<br>`metadata` (dict, 可选) | `memories` (array, 必需):<br> - `memory_id` (str, 必需)<br> - `memory_content` (str, 必需)<br> - `metadata` (dict, 可选) |
|
||||
| **DeleteMemoryOp** | BaseMemoryToolOp | 无 | `memory_id` (str, 必需) | `memory_ids` (array[str], 必需) |
|
||||
| **VectorRetrieveMemoryOp** | BaseMemoryToolOp | `enable_summary_memory` (bool, 默认: False)<br>`add_memory_type_target` (bool, 默认: False)<br>`top_k` (int, 默认: 20) | `query` (str, 必需)<br>`memory_type` (str, 可选, 枚举: [identity, personal, procedural])<br>`memory_target` (str, 可选) | `query_items` (array, 必需):<br> - `query` (str, 必需)<br> - `memory_type` (str, 可选)<br> - `memory_target` (str, 可选) |
|
||||
| **AddMetaMemoryOp** | BaseMemoryToolOp | 无 | `memory_type` (str, 必需, 枚举: [personal, procedural])<br>`memory_target` (str, 必需) | `meta_memories` (array, 必需):<br> - `memory_type` (str, 必需)<br> - `memory_target` (str, 必需) |
|
||||
| **ReadMetaMemoryOp** | BaseMemoryToolOp | `enable_tool_memory` (bool, 默认: False)<br>`enable_identity_memory` (bool, 默认: False) | 无(无输入schema) | N/A (enable_multiple=False) |
|
||||
| **AddHistoryMemoryOp** | BaseMemoryToolOp | 无 | `messages` (array[object], 必需) | N/A (enable_multiple=False) |
|
||||
| **ReadHistoryMemoryOp** | BaseMemoryToolOp | 无 | `memory_id` (str, 必需) | `memory_ids` (array[str], 必需) |
|
||||
| **AddSummaryMemoryOp** | AddMemoryOp | 无(继承自AddMemoryOp) | `summary_memory` (str, 必需)<br>`metadata` (dict, 可选) | N/A (enable_multiple=False) |
|
||||
| **ReadIdentityMemoryOp** | BaseMemoryToolOp | 无 | 无(无输入schema) | N/A (enable_multiple=False) |
|
||||
| **UpdateIdentityMemoryOp** | BaseMemoryToolOp | 无 | `identity_memory` (str, 必需) | N/A (enable_multiple=False) |
|
||||
| **ThinkToolOp** | BaseAsyncToolOp | `add_output_reflection` (bool, 默认: False) | `reflection` (str, 必需) | N/A |
|
||||
| **HandsOffOp** | BaseMemoryToolOp | 无 | `memory_type` (str, 必需, 枚举: [identity, personal, procedural, tool])<br>`memory_target` (str, 必需) | `memory_tasks` (array, 必需):<br> - `memory_type` (str, 必需)<br> - `memory_target` (str, 必需) |
|
||||
|
||||
### 4.3 Agent层设计
|
||||
|
||||
#### 4.3.1 基类:BaseMemoryAgentOp
|
||||
|
||||
Agent层构建在Tool层之上,封装复杂的记忆管理逻辑。每个Agent通过组合多个Tool实现特定的记忆管理任务。
|
||||
|
||||
#### 4.3.2 Agent操作列表
|
||||
|
||||
以下是所有Agent操作的完整定义,包括初始化参数、调用参数和可用工具:
|
||||
|
||||
| Agent类 | 继承自 | 初始化参数(基类外) | Tool Call参数 | 可用工具 |
|
||||
|--------------------------------|-------------------|------------------------------------------------------------------------------------|-----------------------------------------------------------------------------------------------------------------------------------------------------------------|--------------------------------------------------------------------------------------------------------------------------|
|
||||
| **PersonalSummaryAgentV1Op** | BaseMemoryAgentOp | None | `workspace_id` (str, required)<br>`memory_target` (str, required)<br>`query` (str, optional)<br>`messages` (array, optional)<br>`ref_memory_id` (str, required) | add_memory<br>update_memory<br>delete_memory<br>vector_retrieve_memory |
|
||||
| **ProceduralSummaryAgentV1Op** | BaseMemoryAgentOp | None | `workspace_id` (str, required)<br>`memory_target` (str, required)<br>`query` (str, optional)<br>`messages` (array, optional)<br>`ref_memory_id` (str, required) | add_memory<br>update_memory<br>delete_memory<br>vector_retrieve_memory |
|
||||
| **ToolSummaryAgentV1Op** | BaseMemoryAgentOp | None | `workspace_id` (str, required)<br>`memory_target` (str, required)<br>`query` (str, optional)<br>`messages` (array, optional)<br>`ref_memory_id` (str, required) | add_memory<br>update_memory<br>vector_retrieve_memory |
|
||||
| **IdentitySummaryAgentV1Op** | BaseMemoryAgentOp | None | `workspace_id` (str, required)<br>`query` (str, optional)<br>`messages` (array, optional) | read_identity_memory<br>update_identity_memory |
|
||||
| **ReMeSummaryAgentV1Op** | BaseMemoryAgentOp | `enable_tool_memory` (bool, 默认: True)<br>`enable_identity_memory` (bool, 默认: True) | `workspace_id` (str, required)<br>`query` (str, optional)<br>`messages` (array, optional) | add_meta_memory<br>add_summary_memory<br>hands_off<br>(内部调用: add_history_memory, read_identity_memory, read_meta_memory) |
|
||||
| **ReMeRetrieveAgentV1Op** | BaseMemoryAgentOp | `enable_tool_memory` (bool, 默认: True) | `workspace_id` (str, required)<br>`query` (str, optional)<br>`messages` (array, optional) | vector_retrieve_memory<br>read_history_memory<br>(内部调用: read_meta_memory) |
|
||||
| **ReMyAgentV1Op** | BaseMemoryAgentOp | `enable_tool_memory` (bool, 默认: True)<br>`enable_identity_memory` (bool, 默认: True) | `workspace_id` (str, required)<br>`query` (str, optional)<br>`messages` (array, optional) | vector_retrieve_memory<br>read_history_memory<br>(内部调用: read_identity_memory, read_meta_memory) |
|
||||
|
||||
### 4.4 Runtime层设计(内部实现)
|
||||
|
||||
Runtime层负责协调Tool和Agent的调用流程,实现记忆的渐进式处理。
|
||||
|
||||
#### 4.4.1 渐进式总结流程(Summary)
|
||||
|
||||
总结流程采用分层处理策略,首先保存历史对话,读取元信息,然后由主Agent协调多个专用Agent完成分类总结。
|
||||
|
||||
**流程结构:**
|
||||
|
||||
```python
|
||||
# Step 1: Save conversation history
|
||||
AddHistoryMemoryOp()
|
||||
|
||||
# Step 2: Load meta information (memory types and targets)
|
||||
ReadMetaMemoryOp()
|
||||
|
||||
# Step 3: Progressive summarization with delegation
|
||||
ReMeSummaryAgentV1Op(tools=[
|
||||
# Add meta memory entries for new memory types/targets
|
||||
AddMetaMemoryOp(list(memory_type, memory_target)),
|
||||
|
||||
# Add general summary memory as fallback
|
||||
AddSummaryMemoryOp(summary_memory),
|
||||
|
||||
# Delegate to specialized summary agents
|
||||
HandsOffOp(list(memory_type, memory_target), agents=[
|
||||
PersonalSummaryAgentV1Op, # Summarize personal memories
|
||||
ProceduralSummaryAgentV1Op, # Summarize procedural memories
|
||||
ToolSummaryAgentV1Op, # Summarize tool-related memories
|
||||
IdentitySummaryAgentV1Op # Update identity memory
|
||||
]),
|
||||
])
|
||||
|
||||
# Specialized agents and their available tools
|
||||
PersonalSummaryAgentV1Op(tools=[AddMemoryOp, UpdateMemoryOp, DeleteMemoryOp, VectorRetrieveMemoryOp])
|
||||
ProceduralSummaryAgentV1Op(tools=[AddMemoryOp, UpdateMemoryOp, DeleteMemoryOp, VectorRetrieveMemoryOp])
|
||||
ToolSummaryAgentV1Op(tools=[AddMemoryOp, UpdateMemoryOp, VectorRetrieveMemoryOp])
|
||||
IdentitySummaryAgentV1Op(tools=[ReadIdentityMemoryOp, UpdateIdentityMemoryOp])
|
||||
```
|
||||
|
||||
#### 4.4.2 渐进式检索流程(Retrieve)
|
||||
|
||||
检索流程采用三层检索策略,类似于技能系统的加载机制,逐层加载和过滤记忆。
|
||||
|
||||
**流程结构:**
|
||||
|
||||
```python
|
||||
# Progressive retrieval with three layers
|
||||
ReMeRetrieveAgentV1Op(tools=[
|
||||
# Layer 0: Load meta memory (all available memory types and targets)
|
||||
ReadMetaMemoryOp(),
|
||||
# Output format example:
|
||||
# - personal(jinli): Information about Jinli's personal life and preferences
|
||||
# - personal(jiaji): Information about Jiaji's background and interests
|
||||
# - personal(jinli&jiaji): Shared memories between Jinli and Jiaji
|
||||
# - procedural(appworld): Procedural knowledge for AppWorld tasks
|
||||
# - procedural(bfcl-v3): Procedural knowledge for BFCL-v3 benchmark
|
||||
# - tool(tool_guidelines): Guidelines for tool usage
|
||||
# - identity(self): Agent's self-identity information
|
||||
|
||||
# Layer 1+2: Vector-based retrieval on structured memories
|
||||
VectorRetrieveMemoryOp(list(memory_type, memory_target, query)),
|
||||
|
||||
# Layer 3: Load full conversation history for specific memory
|
||||
ReadHistoryMemoryOp(ref_memory_id),
|
||||
])
|
||||
```
|
||||
|
||||
**与技能系统的类比:**
|
||||
|
||||
```python
|
||||
# Skill system hierarchy (for reference)
|
||||
load_meta_skills # Load skill metadata
|
||||
load_skills # Load skill implementations
|
||||
load_reference_skills # Load detailed skill documentation
|
||||
execute_shell # Execute actual commands
|
||||
```
|
||||
|
||||
## 五、扩展设计与实验方向
|
||||
|
||||
### 5.1 Summary Memory机制
|
||||
|
||||
Summary Memory作为通用维度的记忆类型,提供兜底的原始对话索引能力。
|
||||
|
||||
**工作流程示例:**
|
||||
|
||||
```txt
|
||||
Step 1: Progressive summarization across sessions
|
||||
session1: List[Message] -> session2: List[Message] -> session3: List[Message] -> ...
|
||||
summary ✓ (always) ✓ (always) ✓ (always)
|
||||
personal ✗ ✗ ✓ (when applicable)
|
||||
procedural ✗ ✓ (when applicable) ✗
|
||||
|
||||
Step 2: Retrieval with fallback strategy
|
||||
vector_retrieve_memory(query, memory_type="personal", memory_target="jinli")
|
||||
-> Search in memory_type: ["personal", "summary"] # Fallback to summary if personal not found
|
||||
```
|
||||
|
||||
**设计优势:**
|
||||
1. Provides a universal dimension for memory extraction across all memory types
|
||||
2. Ensures fallback indexing of original conversations when specific meta memory is not available
|
||||
3. Maintains conversation context even when specialized memory extraction fails
|
||||
|
||||
### 5.2 Thinking参数实验
|
||||
|
||||
探索不同的模型推理能力增强方案,受AgentScope和Claude启发。
|
||||
|
||||
#### 5.2.1 Thinking参数设计
|
||||
|
||||
```python
|
||||
async def record_to_memory(
|
||||
self,
|
||||
thinking: str,
|
||||
content: list[str],
|
||||
**kwargs: Any,
|
||||
) -> ToolResponse:
|
||||
"""Use this function to record important information that you may
|
||||
need later. The target content should be specific and concise, e.g.
|
||||
who, when, where, do what, why, how, etc.
|
||||
|
||||
Args:
|
||||
thinking (`str`):
|
||||
Your thinking and reasoning about what to record
|
||||
content (`list[str]`):
|
||||
The content to remember, which is a list of strings.
|
||||
"""
|
||||
```
|
||||
|
||||
#### 5.2.2 实验对比方案
|
||||
|
||||
| 方案类型 | 说明 | 灵感来源 |
|
||||
|-------------------------------|--------------------------------------------|----------------|
|
||||
| Thinking Model | Native reasoning-capable models (e.g., o1) | OpenAI |
|
||||
| Instruct Model | Standard instruction-following models | Baseline |
|
||||
| Instruct Model + Thinking Params | Add thinking parameter to tool schema | AgentScope |
|
||||
| Instruct Model + Thinking Tool | Dedicated thinking tool for explicit reasoning | Claude |
|
||||
|
||||
### 5.3 多项操作模式实验
|
||||
|
||||
对比单次调用和批量调用的性能与准确性差异。
|
||||
|
||||
**两种模式对比:**
|
||||
|
||||
| 模式 | Tool调用方式 | Model调用次数 | 优势 | 劣势 |
|
||||
|--------------|----------------------------|---------------|------------------------------|--------------------------|
|
||||
| 单项模式 | Single-item per call | Multiple | Fine-grained control | Higher latency, more tokens |
|
||||
| 多项模式 | Batch multiple items | Single | Lower latency, fewer tokens | Potential batch errors |
|
||||
|
||||
**实验目标:**
|
||||
- Evaluate accuracy: single vs. batch operations
|
||||
- Measure latency and token efficiency
|
||||
- Identify optimal use cases for each mode
|
||||
|
||||
### 5.4 多版本与扩展性
|
||||
|
||||
支持从基类继承实现自定义Agent,便于团队协作和功能迭代。
|
||||
|
||||
**扩展示例:**
|
||||
|
||||
```python
|
||||
# Version 2 implementations by different team members
|
||||
PersonalSummaryAgentV2Op / PersonalRetrieveAgentV2Op # @weikang
|
||||
ProceduralSummaryAgentV2Op / ProceduralRetrieveAgentV2Op # @zouyin
|
||||
|
||||
# Inherit from BaseMemoryAgentOp
|
||||
class PersonalSummaryAgentV2Op(BaseMemoryAgentOp):
|
||||
"""Enhanced personal memory summarization with improved algorithms"""
|
||||
pass
|
||||
```
|
||||
|
||||
### 5.5 文件系统集成(未来方向)
|
||||
|
||||
探索将文件操作能力集成到记忆系统中,支持基于文件的记忆管理。
|
||||
|
||||
**挑战与考虑:**
|
||||
|
||||
1. **操作适配性**:Current operations (retrieve/add/update/delete) need adaptation for file-based storage
|
||||
2. **工具选择**:Consider file operation tools: `grep`, `glob`, `ls`, `read_file`, `write_file`, `edit_file`
|
||||
3. **模型能力**:Base models have limited file operation capabilities; `qwen3-code` shows better performance
|
||||
|
||||
**潜在架构:**
|
||||
|
||||
```python
|
||||
# File-based memory operations
|
||||
FileMemoryOp(tools=[
|
||||
grep, # Search within files
|
||||
glob, # File pattern matching
|
||||
ls, # List directory contents
|
||||
read_file, # Read file contents
|
||||
write_file, # Write new memory files
|
||||
edit_file, # Update existing memory files
|
||||
])
|
||||
```
|
||||
|
||||
### 5.6 自我修改上下文
|
||||
|
||||
支持Agent动态修改自身的上下文状态,实现自适应记忆管理。
|
||||
|
||||
**实现方式:**
|
||||
|
||||
1. **Summary Agent 主动修改**:
|
||||
- `add_meta_memory` directly modifies agent context
|
||||
- Updates available memory types and targets during execution
|
||||
|
||||
2. **ReMy Agent 被动修改**:
|
||||
- Retrieves `identity_memory` at each interaction
|
||||
- Dynamically updates self-state based on retrieved identity
|
||||
- Enables adaptive behavior based on accumulated identity knowledge
|
||||
|
||||
## ReMe V2 开发路线图与实施计划
|
||||
|
||||
### 技术改造阶段
|
||||
1. **代码整合与兼容**:合并flowllm中reme必要的代码,保留现在server-client的依赖,兼容现在各个仓库的依赖代码
|
||||
2. **核心接口重构**:新的ReMe接口设计,支持summary,retrieve,context_offload, context_reload 4个核心接口
|
||||
3. **Agentic算法升级**:新的agentic算法方案开发
|
||||
|
||||
### 评估验证阶段
|
||||
4. **Benchmark测试**
|
||||
- halumem
|
||||
- locomo
|
||||
- longmemevel
|
||||
- personal-v2 ?
|
||||
- appworld/bfcl-v3
|
||||
|
||||
### 发布推广阶段
|
||||
5. **技术报告**撰写与发布
|
||||
6. **生态更新**:更新各个仓库的依赖代码
|
||||
- agentscope
|
||||
- agentscope-runtime
|
||||
- evotraders
|
||||
- alias(tool-memory)
|
||||
- agentscope-java
|
||||
- AgentEvolver
|
||||
- cookbook: reme procedural memory paper
|
||||
- tool-memory-upgrade(将要合并)
|
||||
|
||||
**里程碑目标**:春节前完成小版本发布
|
||||
|
||||
---
|
||||
|
||||
## ReMe V2 核心竞争优势
|
||||
|
||||
### 1. 渐进式 Agentic Memory 架构【核心创新】
|
||||
融合了多种记忆的渐进式agentic方案,实现从短期到长期记忆的智能化演进
|
||||
|
||||
### 2. 全生命周期记忆管理
|
||||
同时支持长期记忆(Long-term Memory)和短期记忆(Working Memory),完整覆盖Agent认知周期
|
||||
|
||||
### 3. 模型
|
||||
提供开源小模型
|
||||
|
||||
### 4. 开发者友好生态
|
||||
1. **简洁接口**:提供简洁的接口设计,全异步接口
|
||||
2. **即开即用**:提供CLI工具,开箱即用的体验
|
||||
3. **生态融合**:提供和AgentScope、LangChain无缝集成的方案
|
||||
4. **高度可扩展**:支持Agentic算法的二次开发与定制
|
||||
|
|
@ -1,3 +0,0 @@
|
|||
1. 如何更好的注册class
|
||||
2. op的返回,使用return 还是 self.output
|
||||
3. 如何把agent的东西放出来
|
||||
16
example.env
16
example.env
|
|
@ -1,11 +1,5 @@
|
|||
FLOW_EMBEDDING_API_KEY=sk-xxxx
|
||||
FLOW_EMBEDDING_BASE_URL=https://xxxx/v1
|
||||
FLOW_LLM_API_KEY=sk-xxxx
|
||||
FLOW_LLM_BASE_URL=https://xxxx/v1
|
||||
|
||||
REME_LLM_API_KEY=sk-xxxx
|
||||
REME_LLM_BASE_URL=https://xxxx/v1
|
||||
REME_EMBEDDING_API_KEY=sk-xxxx
|
||||
REME_EMBEDDING_BASE_URL=https://xxxx/v1
|
||||
|
||||
TAVILY_API_KEY=xxxx
|
||||
LLM_API_KEY=sk-xxxx
|
||||
LLM_BASE_URL=https://xxxx/v1
|
||||
#EMBEDDING_API_KEY=sk-xxxx
|
||||
#EMBEDDING_BASE_URL=https://xxxx/v1
|
||||
#TAVILY_API_KEY=xxxx
|
||||
|
|
|
|||
|
|
@ -77,7 +77,11 @@ dev = [
|
|||
]
|
||||
|
||||
full = [
|
||||
"reme_ai[dev,ray]"
|
||||
"reme_ai[dev,ray,light]",
|
||||
]
|
||||
|
||||
light = [
|
||||
"agentscope==1.0.16.dev0",
|
||||
]
|
||||
|
||||
[tool.setuptools.packages.find]
|
||||
|
|
|
|||
|
|
@ -5,10 +5,8 @@ from . import core
|
|||
from . import extension
|
||||
from . import memory
|
||||
from .reme import ReMe
|
||||
from .reme_cli import ReMeCli
|
||||
from .reme_fb import ReMeFb
|
||||
|
||||
__version__ = "0.3.0.2"
|
||||
__version__ = "0.3.0.6b3"
|
||||
|
||||
__all__ = [
|
||||
"config",
|
||||
|
|
@ -16,8 +14,6 @@ __all__ = [
|
|||
"extension",
|
||||
"memory",
|
||||
"ReMe",
|
||||
"ReMeCli",
|
||||
"ReMeFb",
|
||||
]
|
||||
|
||||
"""
|
||||
|
|
|
|||
|
|
@ -1,43 +1,32 @@
|
|||
backend: cmd
|
||||
working_dir: .reme
|
||||
|
||||
llms:
|
||||
as_llms:
|
||||
default:
|
||||
backend: openai
|
||||
model_name: qwen3.5-plus
|
||||
request_interval: 1
|
||||
|
||||
as_llm_formatters:
|
||||
default:
|
||||
backend: openai
|
||||
|
||||
embedding_models:
|
||||
default:
|
||||
backend: openai
|
||||
model_name: text-embedding-v4
|
||||
dimensions: 1024
|
||||
enable_cache: true
|
||||
use_dimensions: false
|
||||
enable_cache: true
|
||||
max_batch_size: 10
|
||||
max_cache_size: 2000
|
||||
max_input_length: 8192
|
||||
|
||||
file_stores:
|
||||
default:
|
||||
backend: chroma
|
||||
# backend: local
|
||||
store_name: reme
|
||||
embedding_model: default
|
||||
fts_enabled: true
|
||||
vector_enabled: false
|
||||
store_name: "reme"
|
||||
|
||||
file_watchers:
|
||||
default:
|
||||
backend: full
|
||||
file_store: default
|
||||
watch_paths: [ ".reme", ".reme/memory" ]
|
||||
suffix_filters: [ ".md" ]
|
||||
recursive: false
|
||||
scan_on_start: true
|
||||
|
||||
token_counters:
|
||||
default:
|
||||
backend: base
|
||||
|
||||
hf:
|
||||
backend: hf
|
||||
model_name: Qwen/Qwen3-Coder-30B-A3B-Instruct
|
||||
use_mirror: true
|
||||
|
|
@ -66,7 +66,7 @@ flows:
|
|||
description: "Whether to enable soft comparison between highest and lowest scoring trajectories (default: true)."
|
||||
enable_similarity_comparison:
|
||||
type: boolean
|
||||
description: "Whether to enable similarity-based comparison between success and failure trajectories (default: true)."
|
||||
description: "Whether to enable similarity-based comparison between success and failure trajectories (default: false)."
|
||||
max_similarity_sequences:
|
||||
type: integer
|
||||
description: "Maximum number of sequences to compare for similarity (default: 5)."
|
||||
|
|
@ -155,6 +155,7 @@ flows:
|
|||
description: "The path to the memories file."
|
||||
required:
|
||||
- dump_file_path
|
||||
|
||||
test:
|
||||
flow_content: TestOp()
|
||||
description: "test"
|
||||
|
|
|
|||
|
|
@ -1,5 +1,7 @@
|
|||
"""Core"""
|
||||
|
||||
from . import as_llm
|
||||
from . import as_llm_formatter
|
||||
from . import embedding
|
||||
from . import enumeration
|
||||
from . import file_store
|
||||
|
|
@ -21,6 +23,8 @@ from .service_context import ServiceContext
|
|||
|
||||
__all__ = [
|
||||
# Submodules
|
||||
"as_llm",
|
||||
"as_llm_formatter",
|
||||
"embedding",
|
||||
"enumeration",
|
||||
"file_watcher",
|
||||
|
|
|
|||
|
|
@ -1,6 +1,7 @@
|
|||
"""High-level entry point for configuring and running ReMe services and flows."""
|
||||
|
||||
import asyncio
|
||||
import os
|
||||
from concurrent.futures import ThreadPoolExecutor
|
||||
from pathlib import Path
|
||||
|
||||
|
|
@ -35,6 +36,8 @@ class Application:
|
|||
enable_logo: bool = True,
|
||||
log_to_console: bool = True,
|
||||
parser: type[PydanticConfigParser] | None = None,
|
||||
default_as_llm_config: dict | None = None,
|
||||
default_as_llm_formatter_config: dict | None = None,
|
||||
default_llm_config: dict | None = None,
|
||||
default_embedding_model_config: dict | None = None,
|
||||
default_vector_store_config: dict | None = None,
|
||||
|
|
@ -55,6 +58,8 @@ class Application:
|
|||
config_path=config_path,
|
||||
enable_logo=enable_logo,
|
||||
log_to_console=log_to_console,
|
||||
default_as_llm_config=default_as_llm_config,
|
||||
default_as_llm_formatter_config=default_as_llm_formatter_config,
|
||||
default_llm_config=default_llm_config,
|
||||
default_embedding_model_config=default_embedding_model_config,
|
||||
default_vector_store_config=default_vector_store_config,
|
||||
|
|
@ -147,6 +152,26 @@ class Application:
|
|||
if self.service_context.service_config.enable_logo:
|
||||
print_logo(service_config=self.service_config)
|
||||
|
||||
for name, config in self.service_config.as_llms.items():
|
||||
if config.backend not in R.as_llms:
|
||||
logger.warning(f"AS LLM backend {config.backend} is not supported.")
|
||||
else:
|
||||
config_dict = config.model_dump(exclude={"backend"})
|
||||
if not config_dict.get("api_key", ""):
|
||||
config_dict["api_key"] = os.getenv("LLM_API_KEY", "")
|
||||
if "client_kwargs" not in config_dict:
|
||||
config_dict["client_kwargs"] = {}
|
||||
if not config_dict["client_kwargs"].get("base_url", ""):
|
||||
config_dict["client_kwargs"]["base_url"] = os.getenv("LLM_BASE_URL", "")
|
||||
self.service_context.as_llms[name] = R.as_llms[config.backend](**config_dict)
|
||||
|
||||
for name, config in self.service_config.as_llm_formatters.items():
|
||||
if config.backend not in R.as_llm_formatters:
|
||||
logger.warning(f"AS LLM formatter backend {config.backend} is not supported.")
|
||||
else:
|
||||
config_dict = config.model_dump(exclude={"backend"})
|
||||
self.service_context.as_llm_formatters[name] = R.as_llm_formatters[config.backend](**config_dict)
|
||||
|
||||
for name, config in self.service_config.llms.items():
|
||||
if config.backend not in R.llms:
|
||||
logger.warning(f"LLM backend {config.backend} is not supported.")
|
||||
|
|
|
|||
9
reme/core/as_llm/__init__.py
Normal file
9
reme/core/as_llm/__init__.py
Normal file
|
|
@ -0,0 +1,9 @@
|
|||
"""Module for registering AgentScope LLM models."""
|
||||
|
||||
from agentscope.model import DashScopeChatModel
|
||||
from agentscope.model import OpenAIChatModel
|
||||
|
||||
from ..registry_factory import R
|
||||
|
||||
R.as_llms.register("openai")(OpenAIChatModel)
|
||||
R.as_llms.register("dashscope")(DashScopeChatModel)
|
||||
9
reme/core/as_llm_formatter/__init__.py
Normal file
9
reme/core/as_llm_formatter/__init__.py
Normal file
|
|
@ -0,0 +1,9 @@
|
|||
"""Module for registering AgentScope LLM formatters."""
|
||||
|
||||
from agentscope.formatter import DashScopeChatFormatter
|
||||
from agentscope.formatter import OpenAIChatFormatter
|
||||
|
||||
from ..registry_factory import R
|
||||
|
||||
R.as_llm_formatters.register("openai")(OpenAIChatFormatter)
|
||||
R.as_llm_formatters.register("dashscope")(DashScopeChatFormatter)
|
||||
|
|
@ -29,7 +29,7 @@ class BaseEmbeddingModel(ABC):
|
|||
api_key: str | None = None,
|
||||
base_url: str | None = None,
|
||||
model_name: str = "",
|
||||
dimensions: int | None = 1024,
|
||||
dimensions: int = 1024,
|
||||
use_dimensions: bool = False,
|
||||
max_batch_size: int = 10,
|
||||
max_retries: int = 3,
|
||||
|
|
@ -81,12 +81,12 @@ class BaseEmbeddingModel(ABC):
|
|||
@property
|
||||
def api_key(self) -> str | None:
|
||||
"""Get API key from environment variable."""
|
||||
return os.getenv("REME_EMBEDDING_API_KEY") or self._api_key
|
||||
return os.getenv("EMBEDDING_API_KEY") or self._api_key
|
||||
|
||||
@property
|
||||
def base_url(self) -> str | None:
|
||||
"""Get base URL from environment variable."""
|
||||
return os.getenv("REME_EMBEDDING_BASE_URL") or self._base_url
|
||||
return os.getenv("EMBEDDING_BASE_URL") or self._base_url
|
||||
|
||||
def _truncate_text(self, text: str) -> str:
|
||||
"""Truncate text to max_input_length if it exceeds the limit."""
|
||||
|
|
@ -99,7 +99,34 @@ class BaseEmbeddingModel(ABC):
|
|||
"""Truncate a list of texts to max_input_length."""
|
||||
return [self._truncate_text(text) for text in texts]
|
||||
|
||||
def _get_cache_key(self, text: str) -> str:
|
||||
def _validate_and_adjust_embedding(self, embedding: list[float]) -> list[float]:
|
||||
"""Validate and adjust embedding dimensions to match expected dimensions.
|
||||
|
||||
Args:
|
||||
embedding: The embedding vector to validate
|
||||
|
||||
Returns:
|
||||
Embedding vector adjusted to match self.dimensions
|
||||
"""
|
||||
actual_len = len(embedding)
|
||||
if actual_len == self.dimensions:
|
||||
return embedding
|
||||
|
||||
elif actual_len < self.dimensions:
|
||||
logger.warning(
|
||||
f"[ACTUAL_EMB_LENGTH]Embedding dimensions {actual_len} is less than expected {self.dimensions}, "
|
||||
f"padding with zeros",
|
||||
)
|
||||
return embedding + [0.0] * (self.dimensions - actual_len)
|
||||
|
||||
else:
|
||||
logger.warning(
|
||||
f"[ACTUAL_EMB_LENGTH]Embedding dimensions {actual_len} is greater than expected {self.dimensions}, "
|
||||
f"truncating to {self.dimensions}",
|
||||
)
|
||||
return embedding[: self.dimensions]
|
||||
|
||||
def _get_cache_key(self, text: str, dimensions: int) -> str:
|
||||
"""Generate a cache key by hashing text + model_name + dimensions.
|
||||
|
||||
This ensures that the same text produces different cache keys when
|
||||
|
|
@ -107,12 +134,13 @@ class BaseEmbeddingModel(ABC):
|
|||
|
||||
Args:
|
||||
text: Input text to hash
|
||||
dimensions: Vector dimensions of the embeddings
|
||||
|
||||
Returns:
|
||||
SHA256 hash combining text, model name, and dimensions
|
||||
"""
|
||||
# Combine text, model_name, and dimensions to create unique cache key
|
||||
cache_string = f"{text}|{self.model_name}|{self.dimensions}"
|
||||
cache_string = f"{text}|{self.model_name}|{dimensions}"
|
||||
return hashlib.sha256(cache_string.encode("utf-8")).hexdigest()
|
||||
|
||||
def _get_cache_file_path(self) -> Path:
|
||||
|
|
@ -164,6 +192,13 @@ class BaseEmbeddingModel(ABC):
|
|||
if cache_key in self._embedding_cache:
|
||||
continue
|
||||
|
||||
if len(embedding) != self.dimensions:
|
||||
logger.warning(
|
||||
f"Embedding dimensions mismatch for cache key {cache_key}, "
|
||||
f"expected {self.dimensions}, got {len(embedding)}",
|
||||
)
|
||||
continue
|
||||
|
||||
# Respect max_cache_size during loading
|
||||
if len(self._embedding_cache) >= self.max_cache_size:
|
||||
logger.info(
|
||||
|
|
@ -204,6 +239,12 @@ class BaseEmbeddingModel(ABC):
|
|||
try:
|
||||
with open(cache_file, "w", encoding="utf-8") as f:
|
||||
for cache_key, embedding in self._embedding_cache.items():
|
||||
if len(embedding) != self.dimensions:
|
||||
logger.warning(
|
||||
f"Embedding dimensions mismatch for cache key {cache_key}, "
|
||||
f"expected {self.dimensions}, got {len(embedding)}",
|
||||
)
|
||||
continue
|
||||
cache_entry = {cache_key: embedding}
|
||||
f.write(json.dumps(cache_entry, ensure_ascii=False) + "\n")
|
||||
|
||||
|
|
@ -223,16 +264,27 @@ class BaseEmbeddingModel(ABC):
|
|||
if not self.enable_cache:
|
||||
return None
|
||||
|
||||
cache_key = self._get_cache_key(text)
|
||||
cache_key = self._get_cache_key(text, self.dimensions)
|
||||
if cache_key in self._embedding_cache:
|
||||
embeddings: list[float] = self._embedding_cache[cache_key]
|
||||
|
||||
# Validate embedding dimensions match expected dimensions
|
||||
if len(embeddings) != self.dimensions:
|
||||
logger.warning(
|
||||
f"Cached embedding dimensions mismatch: expected {self.dimensions}, "
|
||||
f"got {len(embeddings)}. Removing invalid cache entry.",
|
||||
)
|
||||
del self._embedding_cache[cache_key]
|
||||
self._cache_misses += 1
|
||||
return None
|
||||
|
||||
# Move to end (most recently used)
|
||||
self._embedding_cache.move_to_end(cache_key)
|
||||
self._cache_hits += 1
|
||||
text_preview = text[:50] + "..." if len(text) > 50 else text
|
||||
logger.info(
|
||||
f"Cache hit for text: '{text_preview}' (hits: {self._cache_hits}, misses: {self._cache_misses})",
|
||||
)
|
||||
return self._embedding_cache[cache_key]
|
||||
logger.info(f"Cache hit for text: {text_preview} (hits: {self._cache_hits}, misses: {self._cache_misses})")
|
||||
return embeddings
|
||||
|
||||
self._cache_misses += 1
|
||||
return None
|
||||
|
||||
|
|
@ -249,9 +301,15 @@ class BaseEmbeddingModel(ABC):
|
|||
if self.max_cache_size <= 0:
|
||||
return
|
||||
|
||||
cache_key = self._get_cache_key(text)
|
||||
cache_key = self._get_cache_key(text, self.dimensions)
|
||||
if len(embedding) != self.dimensions:
|
||||
logger.warning(
|
||||
f"[PUT_TO_CACHE] Embedding dimensions mismatch for cache key {cache_key}, "
|
||||
f"expected {self.dimensions}, got real length {len(embedding)}",
|
||||
)
|
||||
return
|
||||
|
||||
# Remove oldest entry if cache is full
|
||||
# Remove the oldest entry if cache is full
|
||||
if len(self._embedding_cache) >= self.max_cache_size and cache_key not in self._embedding_cache:
|
||||
self._embedding_cache.popitem(last=False)
|
||||
|
||||
|
|
@ -299,7 +357,7 @@ class BaseEmbeddingModel(ABC):
|
|||
for i in range(self.max_retries):
|
||||
try:
|
||||
result = await self._get_embeddings([truncated_text], **kwargs)
|
||||
embedding = result[0]
|
||||
embedding = self._validate_and_adjust_embedding(result[0])
|
||||
# Store in cache
|
||||
self._put_to_cache(truncated_text, embedding)
|
||||
return embedding
|
||||
|
|
@ -345,8 +403,9 @@ class BaseEmbeddingModel(ABC):
|
|||
if batch_embeddings:
|
||||
# Store results and cache them
|
||||
for orig_idx, text, embedding in zip(batch_indices, batch_texts, batch_embeddings):
|
||||
results[orig_idx] = embedding
|
||||
self._put_to_cache(text, embedding)
|
||||
adjusted_embedding = self._validate_and_adjust_embedding(embedding)
|
||||
results[orig_idx] = adjusted_embedding
|
||||
self._put_to_cache(text, adjusted_embedding)
|
||||
break
|
||||
except Exception as e:
|
||||
logger.error(f"Model {self.model_name} batch failed: {e}")
|
||||
|
|
@ -371,7 +430,7 @@ class BaseEmbeddingModel(ABC):
|
|||
for i in range(self.max_retries):
|
||||
try:
|
||||
result = self._get_embeddings_sync([truncated_text], **kwargs)
|
||||
embedding = result[0]
|
||||
embedding = self._validate_and_adjust_embedding(result[0])
|
||||
# Store in cache
|
||||
self._put_to_cache(truncated_text, embedding)
|
||||
return embedding
|
||||
|
|
@ -417,8 +476,9 @@ class BaseEmbeddingModel(ABC):
|
|||
if batch_embeddings:
|
||||
# Store results and cache them
|
||||
for orig_idx, text, embedding in zip(batch_indices, batch_texts, batch_embeddings):
|
||||
results[orig_idx] = embedding
|
||||
self._put_to_cache(text, embedding)
|
||||
adjusted_embedding = self._validate_and_adjust_embedding(embedding)
|
||||
results[orig_idx] = adjusted_embedding
|
||||
self._put_to_cache(text, adjusted_embedding)
|
||||
break
|
||||
except Exception as exc:
|
||||
logger.error(f"Model {self.model_name} batch failed: {exc}")
|
||||
|
|
|
|||
|
|
@ -1,6 +1,7 @@
|
|||
"""ChromaDB storage backend for file store."""
|
||||
|
||||
import json
|
||||
import random
|
||||
import time
|
||||
from pathlib import Path
|
||||
|
||||
|
|
@ -355,12 +356,41 @@ class ChromaFileStore(BaseFileStore):
|
|||
where_filter = {"source": {"$in": [s.value for s in sources]}}
|
||||
|
||||
# Perform vector search
|
||||
results = self.chunks_collection.query(
|
||||
query_embeddings=[query_embedding],
|
||||
n_results=limit,
|
||||
where=where_filter,
|
||||
include=["documents", "metadatas", "distances"],
|
||||
)
|
||||
try:
|
||||
results = self.chunks_collection.query(
|
||||
query_embeddings=[query_embedding],
|
||||
n_results=limit,
|
||||
where=where_filter,
|
||||
include=["documents", "metadatas", "distances"],
|
||||
)
|
||||
except Exception as e:
|
||||
logger.error(f"Vector search failed: {e}, falling back to random results")
|
||||
# Fallback: get some documents without vector search and assign random scores
|
||||
try:
|
||||
fallback_results = self.chunks_collection.get(
|
||||
where=where_filter,
|
||||
limit=limit,
|
||||
include=["documents", "metadatas"],
|
||||
)
|
||||
search_results = []
|
||||
if fallback_results["ids"]:
|
||||
for i, _ in enumerate(fallback_results["ids"]):
|
||||
metadata = fallback_results["metadatas"][i]
|
||||
search_results.append(
|
||||
MemorySearchResult(
|
||||
path=metadata["path"],
|
||||
start_line=metadata["start_line"],
|
||||
end_line=metadata["end_line"],
|
||||
score=random.uniform(0.3, 0.7), # Random score in middle range
|
||||
snippet=fallback_results["documents"][i],
|
||||
source=MemorySource(metadata["source"]),
|
||||
raw_metric=None,
|
||||
),
|
||||
)
|
||||
return search_results
|
||||
except Exception as fallback_e:
|
||||
logger.error(f"Fallback search also failed: {fallback_e}")
|
||||
return []
|
||||
|
||||
search_results = []
|
||||
if results["ids"] and results["ids"][0]:
|
||||
|
|
@ -430,7 +460,7 @@ class ChromaFileStore(BaseFileStore):
|
|||
# ChromaDB where_document uses $contains for substring matching (case-sensitive)
|
||||
# Use multiple case variants to improve recall
|
||||
if len(word_variants_list) == 1:
|
||||
where_document = {"$contains": word_variants_list[0]}
|
||||
where_document: dict = {"$contains": word_variants_list[0]}
|
||||
else:
|
||||
where_document = {"$or": [{"$contains": w} for w in word_variants_list]}
|
||||
|
||||
|
|
|
|||
|
|
@ -259,6 +259,8 @@ class LocalFileStore(BaseFileStore):
|
|||
if not query_embedding:
|
||||
return []
|
||||
|
||||
expected_dim = self.embedding_dim
|
||||
|
||||
# Collect candidate chunks with embeddings
|
||||
candidates = [
|
||||
chunk for chunk in self._chunks.values() if (not sources or chunk.source in sources) and chunk.embedding
|
||||
|
|
@ -267,9 +269,29 @@ class LocalFileStore(BaseFileStore):
|
|||
if not candidates:
|
||||
return []
|
||||
|
||||
# Validate and fix chunk embedding dimensions
|
||||
valid_embeddings = []
|
||||
for chunk in candidates:
|
||||
emb = chunk.embedding
|
||||
emb_len = len(emb)
|
||||
if emb_len != expected_dim:
|
||||
if emb_len < expected_dim:
|
||||
emb = emb + [0.0] * (expected_dim - emb_len)
|
||||
logger.warning(
|
||||
f"Chunk embedding dimension {emb_len} < expected {expected_dim}, "
|
||||
f"padded with zeros (chunk_id={chunk.id})",
|
||||
)
|
||||
else:
|
||||
emb = emb[:expected_dim]
|
||||
logger.warning(
|
||||
f"Chunk embedding dimension {emb_len} > expected {expected_dim}, "
|
||||
f"truncated to {expected_dim} (chunk_id={chunk.id})",
|
||||
)
|
||||
valid_embeddings.append(emb)
|
||||
|
||||
# Build embedding matrix and compute similarities in batch
|
||||
query_array = np.array([query_embedding]) # Shape: (1, emb_size)
|
||||
chunk_embeddings = np.array([chunk.embedding for chunk in candidates]) # Shape: (n, emb_size)
|
||||
chunk_embeddings = np.array(valid_embeddings) # Shape: (n, emb_size)
|
||||
similarities = batch_cosine_similarity(query_array, chunk_embeddings)[0] # Shape: (n,)
|
||||
|
||||
# Build results
|
||||
|
|
|
|||
|
|
@ -140,35 +140,63 @@ class BaseFileWatcher:
|
|||
else:
|
||||
logger.info("[SCAN_ON_START] No existing files found matching watch criteria")
|
||||
|
||||
files: list[str] = await self.file_store.list_files(MemorySource.MEMORY)
|
||||
for file_path in files:
|
||||
chunks = await self.file_store.get_file_chunks(file_path, MemorySource.MEMORY)
|
||||
logger.info(f"Found existing file: {file_path}, {len(chunks)} chunks")
|
||||
if self.file_store is not None:
|
||||
files: list[str] = await self.file_store.list_files(MemorySource.MEMORY)
|
||||
for file_path in files:
|
||||
chunks = await self.file_store.get_file_chunks(file_path, MemorySource.MEMORY)
|
||||
logger.info(f"Found existing file: {file_path}, {len(chunks)} chunks")
|
||||
|
||||
async def _interruptible_sleep(self, seconds: float):
|
||||
"""Sleep that can be interrupted by stop_event."""
|
||||
try:
|
||||
await asyncio.wait_for(self._stop_event.wait(), timeout=seconds)
|
||||
except asyncio.TimeoutError:
|
||||
pass # Normal timeout, continue
|
||||
|
||||
async def _watch_loop(self):
|
||||
"""Core monitoring loop"""
|
||||
"""Core monitoring loop with auto-restart on failure"""
|
||||
if not self.watch_paths:
|
||||
logger.warning("No watch paths specified")
|
||||
return
|
||||
|
||||
try:
|
||||
async for changes in awatch(
|
||||
*self.watch_paths,
|
||||
watch_filter=self.watch_filter,
|
||||
recursive=self.recursive,
|
||||
debounce=self.debounce,
|
||||
stop_event=self._stop_event,
|
||||
):
|
||||
if self._stop_event.is_set():
|
||||
break
|
||||
while not self._stop_event.is_set():
|
||||
# Filter out non-existent paths before each watch attempt
|
||||
valid_paths = [p for p in self.watch_paths if Path(p).exists()]
|
||||
|
||||
await self.on_changes(changes)
|
||||
except FileNotFoundError as e:
|
||||
# Watch path was deleted, this is expected during cleanup
|
||||
logger.debug(f"Watch path no longer exists: {e}")
|
||||
except Exception as e:
|
||||
# Log other exceptions but don't crash
|
||||
logger.error(f"Error in watch loop: {e}", exc_info=True)
|
||||
if not valid_paths:
|
||||
logger.warning("No valid watch paths exist, waiting 10 seconds before retry...")
|
||||
await self._interruptible_sleep(10)
|
||||
continue
|
||||
|
||||
invalid_paths = set(self.watch_paths) - set(valid_paths)
|
||||
if invalid_paths:
|
||||
logger.warning(f"Skipping non-existent paths: {invalid_paths}")
|
||||
|
||||
try:
|
||||
logger.info(f"Starting watch on valid paths: {valid_paths}")
|
||||
async for changes in awatch(
|
||||
*valid_paths,
|
||||
watch_filter=self.watch_filter,
|
||||
recursive=self.recursive,
|
||||
debounce=self.debounce,
|
||||
stop_event=self._stop_event,
|
||||
):
|
||||
if self._stop_event.is_set():
|
||||
break
|
||||
|
||||
await self.on_changes(changes)
|
||||
|
||||
except FileNotFoundError as e:
|
||||
# Watch path was deleted during monitoring
|
||||
logger.error(f"Watch path no longer exists: {e}, restarting in 10 seconds...")
|
||||
if not self._stop_event.is_set():
|
||||
await self._interruptible_sleep(10)
|
||||
|
||||
except Exception as e:
|
||||
# Log other exceptions and restart
|
||||
logger.error(f"Error in watch loop: {e}, restarting in 10 seconds...", exc_info=True)
|
||||
if not self._stop_event.is_set():
|
||||
await self._interruptible_sleep(10)
|
||||
|
||||
async def _on_changes(self, changes: set[tuple[Change, str]]):
|
||||
"""Callback method to handle file changes"""
|
||||
|
|
|
|||
|
|
@ -141,6 +141,7 @@ class DeltaFileWatcher(BaseFileWatcher):
|
|||
async def _on_changes(self, changes: set[tuple[Change, str]]):
|
||||
"""Handle file changes with incremental synchronization."""
|
||||
self.dirty = True
|
||||
await self.file_store.clear_all()
|
||||
|
||||
for change_type, path in changes:
|
||||
if change_type == Change.added:
|
||||
|
|
|
|||
|
|
@ -44,6 +44,8 @@ class FullFileWatcher(BaseFileWatcher):
|
|||
async def _on_changes(self, changes: set[tuple[Change, str]]):
|
||||
"""Handle file changes with full synchronization"""
|
||||
self.dirty = True
|
||||
await self.file_store.clear_all()
|
||||
|
||||
for change_type, path in changes:
|
||||
if change_type in [Change.added, Change.modified]:
|
||||
file_meta = await self._build_file_metadata(path)
|
||||
|
|
|
|||
|
|
@ -50,12 +50,12 @@ class BaseLLM(ABC):
|
|||
@property
|
||||
def api_key(self) -> str | None:
|
||||
"""Get API key from environment variable."""
|
||||
return os.getenv("REME_LLM_API_KEY") or self._api_key
|
||||
return os.getenv("LLM_API_KEY") or self._api_key
|
||||
|
||||
@property
|
||||
def base_url(self) -> str | None:
|
||||
"""Get base URL from environment variable."""
|
||||
return os.getenv("REME_LLM_BASE_URL") or self._base_url
|
||||
return os.getenv("LLM_BASE_URL") or self._base_url
|
||||
|
||||
@staticmethod
|
||||
def _accumulate_tool_call_chunk(tool_call, ret_tools: list[ToolCall]):
|
||||
|
|
|
|||
|
|
@ -7,6 +7,8 @@ from abc import ABCMeta
|
|||
from pathlib import Path
|
||||
from typing import Callable, Optional, Any
|
||||
|
||||
from agentscope.formatter import FormatterBase
|
||||
from agentscope.model import ChatModelBase
|
||||
from loguru import logger
|
||||
from tqdm import tqdm
|
||||
|
||||
|
|
@ -42,6 +44,8 @@ class BaseOp(metaclass=ABCMeta):
|
|||
language: str = "",
|
||||
prompt_name: str = "",
|
||||
prompt_path: str = "",
|
||||
as_llm: str | ChatModelBase = "default",
|
||||
as_llm_formatter: str | FormatterBase = "default",
|
||||
llm: str | BaseLLM = "default",
|
||||
embedding_model: str | BaseEmbeddingModel = "default",
|
||||
vector_store: str | BaseVectorStore = "default",
|
||||
|
|
@ -64,6 +68,8 @@ class BaseOp(metaclass=ABCMeta):
|
|||
self.language = language
|
||||
self.prompt = self._get_prompt_handler(prompt_name, prompt_path)
|
||||
|
||||
self._as_llm = as_llm
|
||||
self._as_llm_formatter = as_llm_formatter
|
||||
self._llm = llm
|
||||
self._embedding_model = embedding_model
|
||||
self._vector_store = vector_store
|
||||
|
|
@ -129,6 +135,20 @@ class BaseOp(metaclass=ABCMeta):
|
|||
"""Access the service configuration."""
|
||||
return self.service_context.service_config
|
||||
|
||||
@property
|
||||
def as_llm(self) -> ChatModelBase:
|
||||
"""Get the AgentScope LLM instance from ServiceContext."""
|
||||
if isinstance(self._as_llm, str):
|
||||
self._as_llm = self.service_context.as_llms[self._as_llm]
|
||||
return self._as_llm
|
||||
|
||||
@property
|
||||
def as_llm_formatter(self) -> FormatterBase:
|
||||
"""Get the AgentScope LLM formatter instance from ServiceContext."""
|
||||
if isinstance(self._as_llm_formatter, str):
|
||||
self._as_llm_formatter = self.service_context.as_llm_formatters[self._as_llm_formatter]
|
||||
return self._as_llm_formatter
|
||||
|
||||
@property
|
||||
def llm(self) -> BaseLLM:
|
||||
"""Get the LLM instance from ServiceContext."""
|
||||
|
|
|
|||
|
|
@ -34,6 +34,8 @@ class RegistryFactory:
|
|||
|
||||
def __init__(self):
|
||||
self.llms = Registry()
|
||||
self.as_llms = Registry()
|
||||
self.as_llm_formatters = Registry()
|
||||
self.embedding_models = Registry()
|
||||
self.vector_stores = Registry()
|
||||
self.file_stores = Registry()
|
||||
|
|
|
|||
|
|
@ -1,5 +1,6 @@
|
|||
"""schema"""
|
||||
|
||||
from .as_msg_stat import AsBlockStat, AsMsgStat
|
||||
from .cut_point_result import CutPointResult
|
||||
from .file_metadata import FileMetadata
|
||||
from .memory_chunk import MemoryChunk
|
||||
|
|
@ -27,6 +28,8 @@ from .truncation_result import TruncationResult
|
|||
from .vector_node import VectorNode
|
||||
|
||||
__all__ = [
|
||||
"AsBlockStat",
|
||||
"AsMsgStat",
|
||||
"CutPointResult",
|
||||
"CmdConfig",
|
||||
"ContentBlock",
|
||||
|
|
|
|||
92
reme/core/schema/as_msg_stat.py
Normal file
92
reme/core/schema/as_msg_stat.py
Normal file
|
|
@ -0,0 +1,92 @@
|
|||
"""Schema definitions for AgentScope message statistics."""
|
||||
|
||||
from pydantic import BaseModel, Field
|
||||
|
||||
_DEFAULT_MAX_BLOCK_TEXT_PREVIEW_LENGTH = 100
|
||||
_DEFAULT_MAX_FORMATTER_TEXT_LENGTH = 2000
|
||||
|
||||
|
||||
class AsBlockStat(BaseModel):
|
||||
"""Statistics and metadata for a single content block in an AgentScope message."""
|
||||
|
||||
block_type: str = Field(default=...)
|
||||
text: str = Field(default="", description="Text content of the block")
|
||||
token_count: int = Field(default=0, description="Token count of the block, including base64 data")
|
||||
|
||||
# For tool_use and tool_result blocks
|
||||
tool_name: str = Field(default="", description="Tool name for tool_use/tool_result blocks")
|
||||
tool_input: str = Field(default="", description="Tool input arguments for tool_use blocks")
|
||||
tool_output: str = Field(default="", description="Tool output for tool_result blocks")
|
||||
|
||||
# For media blocks
|
||||
media_url: str = Field(default="", description="URL for image/audio/video blocks")
|
||||
|
||||
@property
|
||||
def preview(self) -> str:
|
||||
"""Return a short preview of the block content."""
|
||||
return self.format(_DEFAULT_MAX_BLOCK_TEXT_PREVIEW_LENGTH)
|
||||
|
||||
def _truncate(self, text: str, max_length: int) -> str:
|
||||
"""Simple truncation with ellipsis."""
|
||||
if len(text) <= max_length:
|
||||
return text
|
||||
return text[:max_length] + "..."
|
||||
|
||||
# pylint: disable=too-many-return-statements
|
||||
def format(self, max_length: int = _DEFAULT_MAX_FORMATTER_TEXT_LENGTH, include_thinking: bool = True) -> str:
|
||||
"""Format block content to string representation.
|
||||
|
||||
Args:
|
||||
max_length: Maximum length of text content in the output.
|
||||
include_thinking: Whether to include thinking block content.
|
||||
|
||||
Returns:
|
||||
Formatted string representation of the block.
|
||||
"""
|
||||
if self.block_type == "text":
|
||||
if not self.text:
|
||||
return ""
|
||||
return f"<text>{self._truncate(self.text, max_length)}</text>"
|
||||
if self.block_type == "thinking":
|
||||
if not include_thinking or not self.text:
|
||||
return ""
|
||||
return f"<thinking>{self._truncate(self.text, max_length)}</thinking>"
|
||||
if self.block_type in ("image", "audio", "video"):
|
||||
content = self.media_url if self.media_url else ""
|
||||
return f"<{self.block_type}>{content}</{self.block_type}>"
|
||||
if self.block_type == "tool_use":
|
||||
content = f"{self.tool_name} params={self._truncate(self.tool_input, max_length)}"
|
||||
return f"<tool_use>{content}</tool_use>"
|
||||
if self.block_type == "tool_result":
|
||||
if not self.tool_output:
|
||||
return ""
|
||||
content = f"{self.tool_name} output={self._truncate(self.tool_output, max_length)}"
|
||||
return f"<tool_result>{content}</tool_result>"
|
||||
return ""
|
||||
|
||||
|
||||
class AsMsgStat(BaseModel):
|
||||
"""Statistics and metadata for a complete AgentScope message."""
|
||||
|
||||
name: str = Field(default=...)
|
||||
role: str = Field(default="")
|
||||
content: list[AsBlockStat] = Field(default_factory=list)
|
||||
timestamp: str = Field(default="")
|
||||
metadata: dict = Field(default_factory=dict)
|
||||
|
||||
@property
|
||||
def total_tokens(self) -> int:
|
||||
"""Return the total token count across all content blocks."""
|
||||
return sum(block.token_count for block in self.content)
|
||||
|
||||
@property
|
||||
def preview(self) -> str:
|
||||
"""Return a short preview of the message content."""
|
||||
return self.format(_DEFAULT_MAX_BLOCK_TEXT_PREVIEW_LENGTH)
|
||||
|
||||
def format(self, max_length: int = _DEFAULT_MAX_FORMATTER_TEXT_LENGTH, include_thinking: bool = True) -> str:
|
||||
"""Format message to string representation."""
|
||||
time_str = f"[{self.timestamp}] " if self.timestamp else ""
|
||||
header = f"{time_str}{self.name or self.role}:"
|
||||
blocks = [block.format(max_length, include_thinking) for block in self.content]
|
||||
return "\n".join([header] + [b for b in blocks if b])
|
||||
|
|
@ -58,69 +58,60 @@ class FlowConfig(ToolCall):
|
|||
cache_expire_hours: float = Field(default=0.1)
|
||||
|
||||
|
||||
class LLMConfig(BaseModel):
|
||||
class BasicConfig(BaseModel):
|
||||
"""Configuration for basic service settings and parameters."""
|
||||
|
||||
model_config = ConfigDict(extra="allow")
|
||||
|
||||
backend: str = Field(default="")
|
||||
|
||||
|
||||
class ModelConfig(BasicConfig):
|
||||
"""Configuration for model-based services with backend and model name."""
|
||||
|
||||
model_name: str = Field(default="")
|
||||
|
||||
|
||||
class LLMConfig(ModelConfig):
|
||||
"""Configuration for Large Language Model backend and model identification."""
|
||||
|
||||
model_config = ConfigDict(extra="allow")
|
||||
|
||||
backend: str = Field(default="")
|
||||
model_name: str = Field(default="")
|
||||
|
||||
|
||||
class EmbeddingModelConfig(BaseModel):
|
||||
class EmbeddingModelConfig(ModelConfig):
|
||||
"""Configuration for embedding model backends and identity."""
|
||||
|
||||
model_config = ConfigDict(extra="allow")
|
||||
|
||||
backend: str = Field(default="")
|
||||
model_name: str = Field(default="")
|
||||
|
||||
|
||||
class VectorStoreConfig(BaseModel):
|
||||
"""Configuration for vector database storage and associated embeddings."""
|
||||
|
||||
model_config = ConfigDict(extra="allow")
|
||||
|
||||
backend: str = Field(default="local")
|
||||
collection_name: str = Field(default="reme")
|
||||
embedding_model: str = Field(default="default")
|
||||
|
||||
|
||||
class FileStoreConfig(BaseModel):
|
||||
"""Configuration for file store database storage and associated embeddings."""
|
||||
|
||||
model_config = ConfigDict(extra="allow")
|
||||
|
||||
backend: str = Field(default="sqlite")
|
||||
store_name: str = Field(default="reme")
|
||||
embedding_model: str = Field(default="default")
|
||||
|
||||
|
||||
class TokenCounterConfig(BaseModel):
|
||||
class TokenCounterConfig(ModelConfig):
|
||||
"""Configuration for token counting services and model mapping."""
|
||||
|
||||
model_config = ConfigDict(extra="allow")
|
||||
|
||||
backend: str = Field(default="base")
|
||||
model_name: str = Field(default="")
|
||||
class StoreConfig(BasicConfig):
|
||||
"""Configuration for storage services with embedding model support."""
|
||||
|
||||
embedding_model: str = Field(default="default")
|
||||
|
||||
|
||||
class FileWatcherConfig(BaseModel):
|
||||
class VectorStoreConfig(StoreConfig):
|
||||
"""Configuration for vector database storage and associated embeddings."""
|
||||
|
||||
collection_name: str = Field(default="reme")
|
||||
|
||||
|
||||
class FileStoreConfig(StoreConfig):
|
||||
"""Configuration for file store database storage and associated embeddings."""
|
||||
|
||||
store_name: str = Field(default="reme")
|
||||
|
||||
|
||||
class FileWatcherConfig(BasicConfig):
|
||||
"""Configuration for file watcher service."""
|
||||
|
||||
model_config = ConfigDict(extra="allow")
|
||||
|
||||
backend: str = Field(default="")
|
||||
file_store: str = Field(default="")
|
||||
watch_paths: list[str] = Field(default_factory=list)
|
||||
|
||||
|
||||
class ServiceConfig(BaseModel):
|
||||
class ServiceConfig(BasicConfig):
|
||||
"""Root configuration schema aggregating all service-level settings and components."""
|
||||
|
||||
model_config = ConfigDict(extra="allow")
|
||||
|
||||
backend: str = Field(default="")
|
||||
app_name: str = Field(default=os.getenv("APP_NAME", "ReMe"))
|
||||
working_dir: str = Field(default=".reme")
|
||||
enable_logo: bool = Field(default=True)
|
||||
|
|
@ -137,6 +128,8 @@ class ServiceConfig(BaseModel):
|
|||
cmd: CmdConfig = Field(default_factory=CmdConfig)
|
||||
ops: dict[str, OpConfig] = Field(default_factory=dict)
|
||||
flows: dict[str, FlowConfig] = Field(default_factory=dict)
|
||||
as_llms: dict[str, BasicConfig] = Field(default_factory=dict)
|
||||
as_llm_formatters: dict[str, BasicConfig] = Field(default_factory=dict)
|
||||
llms: dict[str, LLMConfig] = Field(default_factory=dict)
|
||||
embedding_models: dict[str, EmbeddingModelConfig] = Field(default_factory=dict)
|
||||
vector_stores: dict[str, VectorStoreConfig] = Field(default_factory=dict)
|
||||
|
|
|
|||
|
|
@ -11,6 +11,8 @@ from .schema import ServiceConfig
|
|||
from .utils import load_env, PydanticConfigParser
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from agentscope.model import ChatModelBase
|
||||
from agentscope.formatter import FormatterBase
|
||||
from .llm import BaseLLM
|
||||
from .embedding import BaseEmbeddingModel
|
||||
from .vector_store import BaseVectorStore
|
||||
|
|
@ -36,6 +38,8 @@ class ServiceContext(BaseDict):
|
|||
config_path: str | None = None,
|
||||
enable_logo: bool = True,
|
||||
log_to_console: bool = True,
|
||||
default_as_llm_config: dict | None = None,
|
||||
default_as_llm_formatter_config: dict | None = None,
|
||||
default_llm_config: dict | None = None,
|
||||
default_embedding_model_config: dict | None = None,
|
||||
default_vector_store_config: dict | None = None,
|
||||
|
|
@ -50,10 +54,10 @@ class ServiceContext(BaseDict):
|
|||
load_env()
|
||||
|
||||
# Update common environment variables for LLM and embedding services.
|
||||
self.update_env("REME_LLM_API_KEY", llm_api_key)
|
||||
self.update_env("REME_LLM_BASE_URL", llm_base_url)
|
||||
self.update_env("REME_EMBEDDING_API_KEY", embedding_api_key)
|
||||
self.update_env("REME_EMBEDDING_BASE_URL", embedding_base_url)
|
||||
self.update_env("LLM_API_KEY", llm_api_key)
|
||||
self.update_env("LLM_BASE_URL", llm_base_url)
|
||||
self.update_env("EMBEDDING_API_KEY", embedding_api_key)
|
||||
self.update_env("EMBEDDING_BASE_URL", embedding_base_url)
|
||||
|
||||
if service_config is None:
|
||||
parser_class = parser if parser is not None else PydanticConfigParser
|
||||
|
|
@ -64,6 +68,10 @@ class ServiceContext(BaseDict):
|
|||
if args:
|
||||
input_args.extend(args)
|
||||
|
||||
if default_as_llm_config:
|
||||
self._update_section_config(kwargs, "as_llms", **default_as_llm_config)
|
||||
if default_as_llm_formatter_config:
|
||||
self._update_section_config(kwargs, "as_llm_formatters", **default_as_llm_formatter_config)
|
||||
if default_llm_config:
|
||||
self._update_section_config(kwargs, "llms", **default_llm_config)
|
||||
if default_embedding_model_config:
|
||||
|
|
@ -90,6 +98,8 @@ class ServiceContext(BaseDict):
|
|||
self.service_config: ServiceConfig = service_config
|
||||
|
||||
self.thread_pool: ThreadPoolExecutor | None = None
|
||||
self.as_llms: dict[str, "ChatModelBase"] = {}
|
||||
self.as_llm_formatters: dict[str, "FormatterBase"] = {}
|
||||
self.llms: dict[str, "BaseLLM"] = {}
|
||||
self.embedding_models: dict[str, "BaseEmbeddingModel"] = {}
|
||||
self.token_counters: dict[str, "BaseTokenCounter"] = {}
|
||||
|
|
|
|||
|
|
@ -11,12 +11,15 @@ from .horse import play_horse_easter_egg
|
|||
from .http_client import HttpClient
|
||||
from .llm_utils import extract_content, format_messages, deduplicate_memories
|
||||
from .logger_utils import init_logger
|
||||
from .std_logger import get_logger as get_std_logger
|
||||
from .logo_utils import print_logo
|
||||
from .mcp_client import MCPClient
|
||||
from .pydantic_config_parser import PydanticConfigParser
|
||||
from .pydantic_utils import create_pydantic_model
|
||||
from .singleton import singleton
|
||||
from .time import timer, get_now_time
|
||||
from .hf_token_counter_utils import get_hf_token_counter
|
||||
from .truncate_text_utils import truncate_text, is_truncated
|
||||
|
||||
__all__ = [
|
||||
"convert_dashscope_to_agentscope",
|
||||
|
|
@ -39,6 +42,7 @@ __all__ = [
|
|||
"format_messages",
|
||||
"deduplicate_memories",
|
||||
"init_logger",
|
||||
"get_std_logger",
|
||||
"print_logo",
|
||||
"MCPClient",
|
||||
"PydanticConfigParser",
|
||||
|
|
@ -46,4 +50,7 @@ __all__ = [
|
|||
"singleton",
|
||||
"timer",
|
||||
"get_now_time",
|
||||
"get_hf_token_counter",
|
||||
"truncate_text",
|
||||
"is_truncated",
|
||||
]
|
||||
|
|
|
|||
23
reme/core/utils/hf_token_counter_utils.py
Normal file
23
reme/core/utils/hf_token_counter_utils.py
Normal file
|
|
@ -0,0 +1,23 @@
|
|||
"""Utility functions for working with text."""
|
||||
|
||||
from agentscope.token import HuggingFaceTokenCounter
|
||||
|
||||
_token_counter = None
|
||||
|
||||
|
||||
def get_hf_token_counter(
|
||||
pretrained_model_name_or_path="Qwen/Qwen2.5-7B-Instruct",
|
||||
use_mirror=True,
|
||||
use_fast=True,
|
||||
trust_remote_code=True,
|
||||
):
|
||||
"""Get or initialize the global token counter instance."""
|
||||
global _token_counter
|
||||
if _token_counter is None:
|
||||
_token_counter = HuggingFaceTokenCounter(
|
||||
pretrained_model_name_or_path=pretrained_model_name_or_path,
|
||||
use_mirror=use_mirror,
|
||||
use_fast=use_fast,
|
||||
trust_remote_code=trust_remote_code,
|
||||
)
|
||||
return _token_counter
|
||||
|
|
@ -18,26 +18,6 @@ def init_logger(log_dir: str = "logs", level: str = "INFO", log_to_console: bool
|
|||
# Remove default handler to avoid duplicate logs
|
||||
logger.remove()
|
||||
|
||||
# Ensure the logging directory exists
|
||||
os.makedirs(log_dir, exist_ok=True)
|
||||
|
||||
# Generate filename based on the current timestamp
|
||||
# Use dashes instead of colons for Windows compatibility
|
||||
current_ts = datetime.now().strftime("%Y-%m-%d_%H-%M-%S")
|
||||
log_filename = f"{current_ts}.log"
|
||||
log_filepath = os.path.join(log_dir, log_filename)
|
||||
|
||||
# Configure file-based logging with rotation and compression
|
||||
logger.add(
|
||||
log_filepath,
|
||||
level=level,
|
||||
rotation="00:00",
|
||||
retention="7 days",
|
||||
compression="zip",
|
||||
encoding="utf-8",
|
||||
format="{time:YYYY-MM-DD HH:mm:ss} | {level} | {file}:{line} | {function} | {message}",
|
||||
)
|
||||
|
||||
# Configure colorized standard output logging if enabled
|
||||
if log_to_console:
|
||||
logger.add(
|
||||
|
|
@ -46,3 +26,27 @@ def init_logger(log_dir: str = "logs", level: str = "INFO", log_to_console: bool
|
|||
format="{time:YYYY-MM-DD HH:mm:ss} | {level} | {file}:{line} | {function} | {message}",
|
||||
colorize=True,
|
||||
)
|
||||
|
||||
# Try to configure file-based logging (skip if permission denied)
|
||||
try:
|
||||
# Ensure the logging directory exists
|
||||
os.makedirs(log_dir, exist_ok=True)
|
||||
|
||||
# Generate filename based on the current timestamp
|
||||
# Use dashes instead of colons for Windows compatibility
|
||||
current_ts = datetime.now().strftime("%Y-%m-%d_%H-%M-%S")
|
||||
log_filename = f"{current_ts}.log"
|
||||
log_filepath = os.path.join(log_dir, log_filename)
|
||||
|
||||
# Configure file-based logging with rotation and compression
|
||||
logger.add(
|
||||
log_filepath,
|
||||
level=level,
|
||||
rotation="00:00",
|
||||
retention="7 days",
|
||||
compression="zip",
|
||||
encoding="utf-8",
|
||||
format="{time:YYYY-MM-DD HH:mm:ss} | {level} | {file}:{line} | {function} | {message}",
|
||||
)
|
||||
except Exception as e:
|
||||
logger.error(f"Error configuring file logging: {e}")
|
||||
|
|
|
|||
120
reme/core/utils/std_logger.py
Normal file
120
reme/core/utils/std_logger.py
Normal file
|
|
@ -0,0 +1,120 @@
|
|||
"""Standard logging module configuration with loguru-like features."""
|
||||
|
||||
import logging
|
||||
import os
|
||||
import sys
|
||||
from datetime import datetime
|
||||
from logging.handlers import TimedRotatingFileHandler
|
||||
|
||||
# Store created logger instances
|
||||
_loggers: dict[str, logging.Logger] = {}
|
||||
|
||||
|
||||
class CustomFormatter(logging.Formatter):
|
||||
"""Custom formatter with colorized output support."""
|
||||
|
||||
# ANSI color codes
|
||||
COLORS = {
|
||||
logging.DEBUG: "\033[36m", # Cyan
|
||||
logging.INFO: "\033[32m", # Green
|
||||
logging.WARNING: "\033[33m", # Yellow
|
||||
logging.ERROR: "\033[31m", # Red
|
||||
logging.CRITICAL: "\033[35m", # Magenta
|
||||
}
|
||||
RESET = "\033[0m"
|
||||
|
||||
def __init__(self, fmt: str, colorize: bool = False):
|
||||
super().__init__(fmt)
|
||||
self.colorize = colorize
|
||||
|
||||
def format(self, record: logging.LogRecord) -> str:
|
||||
# Add custom attribute: simplified filename and line number
|
||||
record.file_line = f"{record.filename}:{record.lineno}"
|
||||
|
||||
if self.colorize:
|
||||
color = self.COLORS.get(record.levelno, self.RESET)
|
||||
record.levelname = f"{color}{record.levelname}{self.RESET}"
|
||||
|
||||
return super().format(record)
|
||||
|
||||
|
||||
def get_loggerv2(
|
||||
name: str = "reme",
|
||||
log_dir: str = "logs",
|
||||
level: str = "INFO",
|
||||
log_to_console: bool = True,
|
||||
log_to_file: bool = True,
|
||||
log_file_prefix: str = "reme",
|
||||
rotation: str = "midnight",
|
||||
retention_days: int = 7,
|
||||
) -> logging.Logger:
|
||||
"""Get a configured logger instance.
|
||||
|
||||
Args:
|
||||
name: Logger name for distinguishing different loggers.
|
||||
log_dir: Directory path for log files.
|
||||
level: Logging level (DEBUG, INFO, WARNING, ERROR, CRITICAL).
|
||||
log_to_console: Whether to output logs to console.
|
||||
log_to_file: Whether to output logs to file.
|
||||
log_file_prefix: Prefix for log file names (e.g., 'reme' -> 'reme_2024-01-01.log').
|
||||
rotation: Log rotation time, defaults to midnight.
|
||||
retention_days: Number of days to retain log files.
|
||||
|
||||
Returns:
|
||||
Configured Logger instance.
|
||||
"""
|
||||
# Return existing logger if already created
|
||||
if name in _loggers:
|
||||
return _loggers[name]
|
||||
|
||||
# Create new logger without using root logger
|
||||
logger = logging.getLogger(name)
|
||||
logger.setLevel(getattr(logging, level.upper(), logging.INFO))
|
||||
logger.propagate = False # Do not propagate to root logger
|
||||
|
||||
# Clear existing handlers
|
||||
logger.handlers.clear()
|
||||
|
||||
# Log format
|
||||
log_format = "%(asctime)s | %(levelname)s | %(file_line)s | %(funcName)s | %(message)s"
|
||||
|
||||
# Configure file logging
|
||||
if log_to_file:
|
||||
try:
|
||||
os.makedirs(log_dir, exist_ok=True)
|
||||
current_ts = datetime.now().strftime("%Y-%m-%d_%H-%M-%S")
|
||||
log_filename = f"{log_file_prefix}_{current_ts}.log"
|
||||
log_filepath = os.path.join(log_dir, log_filename)
|
||||
|
||||
file_handler = TimedRotatingFileHandler(
|
||||
log_filepath,
|
||||
when=rotation,
|
||||
interval=1,
|
||||
backupCount=retention_days,
|
||||
encoding="utf-8",
|
||||
)
|
||||
file_handler.setLevel(getattr(logging, level.upper(), logging.INFO))
|
||||
file_handler.setFormatter(CustomFormatter(log_format, colorize=False))
|
||||
file_handler.suffix = "%Y-%m-%d"
|
||||
logger.addHandler(file_handler)
|
||||
|
||||
except Exception as e:
|
||||
logger.error(f"Error configuring file logging: {e}")
|
||||
|
||||
# Configure console logging
|
||||
if log_to_console:
|
||||
console_handler = logging.StreamHandler(sys.stdout)
|
||||
console_handler.setLevel(getattr(logging, level.upper(), logging.INFO))
|
||||
console_handler.setFormatter(CustomFormatter(log_format, colorize=True))
|
||||
logger.addHandler(console_handler)
|
||||
|
||||
# Cache logger
|
||||
_loggers[name] = logger
|
||||
return logger
|
||||
|
||||
|
||||
def get_logger():
|
||||
"""Get a configured logger instance using loguru."""
|
||||
from loguru import logger
|
||||
|
||||
return logger
|
||||
55
reme/core/utils/truncate_text_utils.py
Normal file
55
reme/core/utils/truncate_text_utils.py
Normal file
|
|
@ -0,0 +1,55 @@
|
|||
"""Utility functions for truncating long text strings."""
|
||||
|
||||
from .std_logger import get_logger
|
||||
|
||||
logger = get_logger()
|
||||
|
||||
TRUNCATION_MARKER_START = "<<<TRUNCATED>>>"
|
||||
TRUNCATION_MARKER_END = "<<<END_TRUNCATED>>>"
|
||||
|
||||
|
||||
def truncate_text(text: str, max_length: int) -> str:
|
||||
"""Truncate text to max length, keeping head and tail portions.
|
||||
|
||||
Args:
|
||||
text: The text to truncate
|
||||
max_length: Maximum allowed length
|
||||
|
||||
Returns:
|
||||
Truncated text with unique markers indicating truncation
|
||||
"""
|
||||
text = str(text) if text else ""
|
||||
if not text:
|
||||
return text
|
||||
|
||||
if len(text) <= max_length:
|
||||
return text
|
||||
|
||||
half_length = max_length // 2
|
||||
truncated_chars = len(text) - max_length
|
||||
logger.debug(
|
||||
"Text truncated: original %d chars, kept head %d + tail %d, removed %d chars.",
|
||||
len(text),
|
||||
half_length,
|
||||
half_length,
|
||||
truncated_chars,
|
||||
)
|
||||
return (
|
||||
f"{text[:half_length]}\n\n{TRUNCATION_MARKER_START} "
|
||||
f"({truncated_chars} characters omitted) "
|
||||
f"{TRUNCATION_MARKER_END}\n\n{text[-half_length:]}"
|
||||
)
|
||||
|
||||
|
||||
def is_truncated(text: str) -> bool:
|
||||
"""Check if the text has been truncated (contains truncation markers).
|
||||
|
||||
Args:
|
||||
text: The text to check
|
||||
|
||||
Returns:
|
||||
bool: True if text contains truncation markers, False otherwise
|
||||
"""
|
||||
if not text:
|
||||
return False
|
||||
return TRUNCATION_MARKER_START in text and TRUNCATION_MARKER_END in text
|
||||
|
|
@ -49,8 +49,8 @@ class ComparativeExtraction(BaseOp):
|
|||
comparative_task_memories.extend(soft_task_memories)
|
||||
|
||||
# Hard comparison: success vs failure (if similarity search is enabled)
|
||||
if self.context.get("enable_similarity_comparison", True) and success_trajectories and failure_trajectories:
|
||||
similar_pairs = self._find_similar_step_sequences(success_trajectories, failure_trajectories)
|
||||
if self.context.get("enable_similarity_comparison", False) and success_trajectories and failure_trajectories:
|
||||
similar_pairs = await self._find_similar_step_sequences(success_trajectories, failure_trajectories)
|
||||
logger.info(f"Found {len(similar_pairs)} similar pairs for hard comparison")
|
||||
|
||||
for success_steps, failure_steps, similarity_score in similar_pairs:
|
||||
|
|
@ -182,7 +182,7 @@ class ComparativeExtraction(BaseOp):
|
|||
else:
|
||||
return trajectory.messages
|
||||
|
||||
def _find_similar_step_sequences(
|
||||
async def _find_similar_step_sequences(
|
||||
self,
|
||||
success_trajectories: List[Trajectory],
|
||||
failure_trajectories: List[Trajectory],
|
||||
|
|
@ -227,8 +227,8 @@ class ComparativeExtraction(BaseOp):
|
|||
"embedding_model",
|
||||
)
|
||||
):
|
||||
success_embeddings = self.vector_store.embedding_model.get_embeddings(success_texts)
|
||||
failure_embeddings = self.vector_store.embedding_model.get_embeddings(failure_texts)
|
||||
success_embeddings = await self.vector_store.get_embeddings(success_texts)
|
||||
failure_embeddings = await self.vector_store.get_embeddings(failure_texts)
|
||||
|
||||
# Calculate similarity and find most similar pairs
|
||||
similarity_threshold = self.context.get("similarity_threshold", 0.5)
|
||||
|
|
|
|||
|
|
@ -1,11 +1,11 @@
|
|||
"""memory"""
|
||||
|
||||
from . import file_based
|
||||
from . import tools
|
||||
from . import vector_tools
|
||||
from . import vector_based
|
||||
|
||||
__all__ = [
|
||||
"file_based",
|
||||
"tools",
|
||||
"vector_tools",
|
||||
"vector_based",
|
||||
]
|
||||
|
|
|
|||
|
|
@ -1,18 +1,13 @@
|
|||
"""File-based memory operations."""
|
||||
"""File-based Memory Module."""
|
||||
|
||||
from .fb_cli import FbCli
|
||||
from .fb_compactor import FbCompactor
|
||||
from .fb_context_checker import FbContextChecker
|
||||
from .fb_summarizer import FbSummarizer
|
||||
from ...core.registry_factory import R
|
||||
from . import components
|
||||
from . import tools
|
||||
from . import utils
|
||||
from .reme_in_memory_memory import ReMeInMemoryMemory
|
||||
|
||||
__all__ = [
|
||||
"FbCli",
|
||||
"FbCompactor",
|
||||
"FbContextChecker",
|
||||
"FbSummarizer",
|
||||
"tools",
|
||||
"utils",
|
||||
"components",
|
||||
"ReMeInMemoryMemory",
|
||||
]
|
||||
|
||||
for name in __all__:
|
||||
op_class = globals()[name]
|
||||
R.ops.register(op_class)
|
||||
|
|
|
|||
13
reme/memory/file_based/components/__init__.py
Normal file
13
reme/memory/file_based/components/__init__.py
Normal file
|
|
@ -0,0 +1,13 @@
|
|||
"""components"""
|
||||
|
||||
from .compactor import Compactor
|
||||
from .context_checker import ContextChecker
|
||||
from .summarizer import Summarizer
|
||||
from .tool_result_compactor import ToolResultCompactor
|
||||
|
||||
__all__ = [
|
||||
"Compactor",
|
||||
"Summarizer",
|
||||
"ContextChecker",
|
||||
"ToolResultCompactor",
|
||||
]
|
||||
79
reme/memory/file_based/components/compactor.py
Normal file
79
reme/memory/file_based/components/compactor.py
Normal file
|
|
@ -0,0 +1,79 @@
|
|||
"""Compactor module for memory compaction operations."""
|
||||
|
||||
from agentscope.agent import ReActAgent
|
||||
from agentscope.message import Msg
|
||||
from agentscope.token import HuggingFaceTokenCounter
|
||||
|
||||
from ..utils import AsMsgHandler
|
||||
from ....core.op import BaseOp
|
||||
from ....core.utils import get_std_logger
|
||||
|
||||
logger = get_std_logger()
|
||||
|
||||
|
||||
class Compactor(BaseOp):
|
||||
"""Compactor class for compacting memory messages."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
memory_compact_threshold: int,
|
||||
token_counter: HuggingFaceTokenCounter,
|
||||
**kwargs,
|
||||
):
|
||||
super().__init__(**kwargs)
|
||||
self.memory_compact_threshold: int = memory_compact_threshold
|
||||
|
||||
self.msg_handler = AsMsgHandler(token_counter=token_counter)
|
||||
|
||||
async def execute(self):
|
||||
messages: list[Msg] = self.context.get("messages", [])
|
||||
previous_summary: str = self.context.get("previous_summary", "")
|
||||
|
||||
if not messages:
|
||||
return ""
|
||||
|
||||
before_token_count = self.msg_handler.count_msgs_token(messages)
|
||||
history_formatted_str: str = self.msg_handler.format_msgs_to_str(
|
||||
messages=messages,
|
||||
memory_compact_threshold=self.memory_compact_threshold,
|
||||
)
|
||||
after_token_count = self.msg_handler.count_str_token(history_formatted_str)
|
||||
logger.info(f"Compactor before_token_count={before_token_count} after_token_count={after_token_count}")
|
||||
|
||||
if not history_formatted_str:
|
||||
logger.warning(f"No history to compact. messages={messages}")
|
||||
return ""
|
||||
|
||||
agent = ReActAgent(
|
||||
name="reme_compactor",
|
||||
model=self.as_llm,
|
||||
sys_prompt=self.get_prompt("system_prompt"),
|
||||
formatter=self.as_llm_formatter,
|
||||
)
|
||||
|
||||
if previous_summary:
|
||||
prefix: str = self.get_prompt("update_user_message_prefix")
|
||||
suffix: str = self.get_prompt("update_user_message_suffix")
|
||||
user_message: str = (
|
||||
f"<conversation>\n{history_formatted_str}\n</conversation>\n\n"
|
||||
f"{prefix}\n\n"
|
||||
f"<previous-summary>\n{previous_summary}\n</previous-summary>\n\n"
|
||||
f"{suffix}"
|
||||
)
|
||||
else:
|
||||
user_message: str = f"<conversation>\n{history_formatted_str}\n</conversation>\n\n" + self.get_prompt(
|
||||
"initial_user_message",
|
||||
)
|
||||
logger.info(f"Compactor sys_prompt={agent.sys_prompt} user_message={user_message}")
|
||||
|
||||
compact_msg: Msg = await agent.reply(
|
||||
Msg(
|
||||
name="reme",
|
||||
role="user",
|
||||
content=user_message,
|
||||
),
|
||||
)
|
||||
|
||||
history_compact: str = compact_msg.get_text_content()
|
||||
logger.info(f"Compactor Result:\n{history_compact}")
|
||||
return history_compact
|
||||
160
reme/memory/file_based/components/compactor.yaml
Normal file
160
reme/memory/file_based/components/compactor.yaml
Normal file
|
|
@ -0,0 +1,160 @@
|
|||
system_prompt: |
|
||||
You are a context compaction assistant. Your role is to create structured summaries of conversations
|
||||
that can be used to restore context in future sessions. Focus on preserving critical information while reducing token count.
|
||||
|
||||
system_prompt_zh: |
|
||||
你是一个上下文压缩助手。你的角色是创建对话的结构化摘要,
|
||||
这些摘要可以在未来会话中用于恢复上下文。专注于保留关键信息,同时减少token数量。
|
||||
|
||||
initial_user_message: |
|
||||
The messages above are a conversation to summarize. Create a structured context checkpoint summary
|
||||
that another LLM will use to continue the work.
|
||||
|
||||
Use this EXACT format:
|
||||
|
||||
## Goal
|
||||
[What is the user trying to accomplish? Can be multiple items if the session covers different tasks.]
|
||||
|
||||
## Constraints & Preferences
|
||||
- [Any constraints, preferences, or requirements mentioned by user]
|
||||
- [Or "(none)" if none were mentioned]
|
||||
|
||||
## Progress
|
||||
### Done
|
||||
- [x] [Completed tasks/changes]
|
||||
|
||||
### In Progress
|
||||
- [ ] [Current work]
|
||||
|
||||
### Blocked
|
||||
- [Issues preventing progress, if any]
|
||||
|
||||
## Key Decisions
|
||||
- **[Decision]**: [Brief rationale]
|
||||
|
||||
## Next Steps
|
||||
1. [Ordered list of what should happen next]
|
||||
|
||||
## Critical Context
|
||||
- [Any data, examples, or references needed to continue]
|
||||
- [Or "(none)" if not applicable]
|
||||
|
||||
Keep each section concise. Preserve exact file paths, function names, and error messages.
|
||||
|
||||
initial_user_message_zh: |
|
||||
上述消息是一场需要总结的对话。创建一个结构化的上下文检查点摘要,
|
||||
以便另一个LLM可以用来继续工作。
|
||||
|
||||
使用此确切格式:
|
||||
|
||||
## 目标
|
||||
[用户试图完成什么?如果会话涵盖不同任务,可以有多个项目。]
|
||||
|
||||
## 约束和偏好
|
||||
- [任何用户提到的约束、偏好或要求]
|
||||
- [或者如果没有提到则为"(none)"]
|
||||
|
||||
## 进展
|
||||
### 已完成
|
||||
- [x] [已完成的任务/更改]
|
||||
|
||||
### 进行中
|
||||
- [ ] [当前工作]
|
||||
|
||||
### 阻塞
|
||||
- [如果有任何阻碍进展的问题]
|
||||
|
||||
## 关键决策
|
||||
- **[决策]**: [简短理由]
|
||||
|
||||
## 下一步
|
||||
1. [接下来应该发生的事情的有序列表]
|
||||
|
||||
## 关键上下文
|
||||
- [任何继续工作所需的数据、示例或参考资料]
|
||||
- [或者如果不适用则为"(none)"]
|
||||
|
||||
保持每个部分简洁。保留确切的文件路径、函数名称和错误消息。
|
||||
|
||||
update_user_message_prefix: |
|
||||
The messages above are NEW conversation messages to incorporate into the existing summary provided in
|
||||
<previous-summary> tags.
|
||||
|
||||
update_user_message_suffix: |
|
||||
Update the existing structured summary with new information. RULES:
|
||||
- PRESERVE all existing information from the previous summary
|
||||
- ADD new progress, decisions, and context from the new messages
|
||||
- UPDATE the Progress section: move items from "In Progress" to "Done" when completed
|
||||
- UPDATE "Next Steps" based on what was accomplished
|
||||
- PRESERVE exact file paths, function names, and error messages
|
||||
- If something is no longer relevant, you may remove it
|
||||
|
||||
Use this EXACT format:
|
||||
|
||||
## Goal
|
||||
[Preserve existing goals, add new ones if the task expanded]
|
||||
|
||||
## Constraints & Preferences
|
||||
- [Preserve existing, add new ones discovered]
|
||||
|
||||
## Progress
|
||||
### Done
|
||||
- [x] [Include previously done items AND newly completed items]
|
||||
|
||||
### In Progress
|
||||
- [ ] [Current work - update based on progress]
|
||||
|
||||
### Blocked
|
||||
- [Current blockers - remove if resolved]
|
||||
|
||||
## Key Decisions
|
||||
- **[Decision]**: [Brief rationale] (preserve all previous, add new)
|
||||
|
||||
## Next Steps
|
||||
1. [Update based on current state]
|
||||
|
||||
## Critical Context
|
||||
- [Preserve important context, add new if needed]
|
||||
|
||||
Keep each section concise. Preserve exact file paths, function names, and error messages.
|
||||
|
||||
update_user_message_prefix_zh: |
|
||||
以上消息是需要整合到现有摘要中的新对话内容,现有摘要位于<previous-summary>标签中。
|
||||
|
||||
update_user_message_suffix_zh: |
|
||||
用新信息更新现有的结构化摘要。规则:
|
||||
- 保留来自先前摘要的所有现有信息
|
||||
- 从新消息中添加新的进展、决策和上下文
|
||||
- 更新进度部分:当完成时将项目从"进行中"移到"已完成"
|
||||
- 根据已完成的内容更新"下一步"
|
||||
- 保留确切的文件路径、函数名称和错误消息
|
||||
- 如果某些内容不再相关,您可以删除它
|
||||
|
||||
使用此确切格式:
|
||||
|
||||
## 目标
|
||||
[保留现有目标,如果任务扩展则添加新目标]
|
||||
|
||||
## 约束和偏好
|
||||
- [保留现有内容,添加发现的新内容]
|
||||
|
||||
## 进展
|
||||
### 已完成
|
||||
- [x] [包含以前完成的项目和新完成的项目]
|
||||
|
||||
### 进行中
|
||||
- [ ] [当前工作 - 根据进展更新]
|
||||
|
||||
### 阻塞
|
||||
- [当前阻塞问题 - 如果解决则删除]
|
||||
|
||||
## 关键决策
|
||||
- **[决策]**: [简短理由](保留所有之前的内容,添加新的)
|
||||
|
||||
## 下一步
|
||||
1. [根据当前状态更新]
|
||||
|
||||
## 关键上下文
|
||||
- [保留重要上下文,如需要则添加新的]
|
||||
|
||||
保持每个部分简洁。保留确切的文件路径、函数名称和错误消息。
|
||||
98
reme/memory/file_based/components/context_checker.py
Normal file
98
reme/memory/file_based/components/context_checker.py
Normal file
|
|
@ -0,0 +1,98 @@
|
|||
"""ContextChecker module for checking context size and splitting messages."""
|
||||
|
||||
from agentscope.message import Msg
|
||||
from agentscope.token import HuggingFaceTokenCounter
|
||||
|
||||
from ..utils import AsMsgHandler
|
||||
from ....core.op import BaseOp
|
||||
from ....core.utils import get_std_logger
|
||||
|
||||
logger = get_std_logger()
|
||||
|
||||
|
||||
class ContextChecker(BaseOp):
|
||||
"""
|
||||
ContextChecker class for checking context size and splitting messages.
|
||||
|
||||
This class analyzes conversation messages to determine if the context
|
||||
exceeds the specified token threshold and splits messages into two groups:
|
||||
those that should be compacted and those to keep in context.
|
||||
|
||||
Attributes:
|
||||
memory_compact_threshold (int): Token count threshold for triggering compaction.
|
||||
memory_compact_reserve (int): Token count to reserve for recent messages.
|
||||
msg_handler (AsMsgHandler): Handler for message processing and token counting.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
memory_compact_threshold: int,
|
||||
memory_compact_reserve: int = 10000,
|
||||
token_counter: HuggingFaceTokenCounter | None = None,
|
||||
**kwargs,
|
||||
):
|
||||
"""
|
||||
Initialize the ContextChecker.
|
||||
|
||||
Args:
|
||||
memory_compact_threshold (int): Token count threshold for triggering
|
||||
compaction. Messages exceeding this threshold will be split.
|
||||
memory_compact_reserve (int): Token count to reserve for recent messages
|
||||
to keep in context. Defaults to 10000 tokens.
|
||||
token_counter (HuggingFaceTokenCounter | None): Token counter for
|
||||
measuring content length. If None, a default counter will be used.
|
||||
**kwargs: Additional keyword arguments passed to BaseOp.
|
||||
"""
|
||||
super().__init__(**kwargs)
|
||||
self.memory_compact_threshold: int = memory_compact_threshold
|
||||
self.memory_compact_reserve: int = memory_compact_reserve
|
||||
assert self.memory_compact_threshold > self.memory_compact_reserve
|
||||
|
||||
self.msg_handler = AsMsgHandler(token_counter=token_counter)
|
||||
|
||||
async def execute(self) -> tuple[list[Msg], list[Msg], bool]:
|
||||
"""
|
||||
Execute context check and split messages.
|
||||
|
||||
Retrieves messages from context and checks if they exceed the token
|
||||
threshold. If so, splits them into messages to compact and messages
|
||||
to keep.
|
||||
|
||||
Context Parameters:
|
||||
messages (list[Msg]): List of conversation messages to check.
|
||||
Retrieved from self.context.get("messages", []).
|
||||
|
||||
Returns:
|
||||
tuple[list[Msg], list[Msg], bool]: A tuple containing:
|
||||
- messages_to_compact (list[Msg]): Older messages that should
|
||||
be compacted/summarized.
|
||||
- messages_to_keep (list[Msg]): Recent messages to keep in context.
|
||||
- is_valid (bool): True if the split is valid (tool calls aligned),
|
||||
False if splitting would break conversation integrity.
|
||||
|
||||
Note:
|
||||
- Returns ([], messages, True) if no compaction is needed.
|
||||
- Ensures conversation pairs (user-assistant) are not split.
|
||||
- is_valid=False indicates tool_use and tool_result are misaligned.
|
||||
"""
|
||||
messages: list[Msg] = self.context.get("messages", [])
|
||||
|
||||
if not messages:
|
||||
logger.info("ContextChecker: No messages to check.")
|
||||
return [], [], True
|
||||
|
||||
messages_to_compact, messages_to_keep, is_valid = self.msg_handler.context_check(
|
||||
messages=messages,
|
||||
memory_compact_threshold=self.memory_compact_threshold,
|
||||
memory_compact_reserve=self.memory_compact_reserve,
|
||||
)
|
||||
|
||||
if messages_to_compact:
|
||||
logger.info(
|
||||
f"ContextChecker Result: "
|
||||
f"to_compact={len(messages_to_compact)}, "
|
||||
f"to_keep={len(messages_to_keep)}, "
|
||||
f"is_valid={is_valid}",
|
||||
)
|
||||
|
||||
return messages_to_compact, messages_to_keep, is_valid
|
||||
80
reme/memory/file_based/components/summarizer.py
Normal file
80
reme/memory/file_based/components/summarizer.py
Normal file
|
|
@ -0,0 +1,80 @@
|
|||
"""Summarizer module for memory summarization operations."""
|
||||
|
||||
import datetime
|
||||
|
||||
from agentscope.agent import ReActAgent
|
||||
from agentscope.message import Msg
|
||||
from agentscope.token import HuggingFaceTokenCounter
|
||||
from agentscope.tool import Toolkit
|
||||
|
||||
from ..utils import AsMsgHandler
|
||||
from ....core.op import BaseOp
|
||||
from ....core.utils import get_std_logger
|
||||
|
||||
logger = get_std_logger()
|
||||
|
||||
|
||||
class Summarizer(BaseOp):
|
||||
"""Summarizer class for summarizing memory messages."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
working_dir: str,
|
||||
memory_dir: str,
|
||||
memory_compact_threshold: int,
|
||||
token_counter: HuggingFaceTokenCounter,
|
||||
toolkit: Toolkit,
|
||||
**kwargs,
|
||||
):
|
||||
super().__init__(**kwargs)
|
||||
self.working_dir: str = working_dir
|
||||
self.memory_dir: str = memory_dir
|
||||
self.memory_compact_threshold: int = memory_compact_threshold
|
||||
|
||||
self.msg_handler = AsMsgHandler(token_counter=token_counter)
|
||||
self.toolkit: Toolkit = toolkit
|
||||
|
||||
async def execute(self):
|
||||
messages: list[Msg] = self.context.get("messages", [])
|
||||
|
||||
if not messages:
|
||||
return ""
|
||||
|
||||
before_token_count = self.msg_handler.count_msgs_token(messages)
|
||||
history_formatted_str: str = self.msg_handler.format_msgs_to_str(
|
||||
messages=messages,
|
||||
memory_compact_threshold=self.memory_compact_threshold,
|
||||
)
|
||||
after_token_count = self.msg_handler.count_str_token(history_formatted_str)
|
||||
logger.info(f"Summarizer before_token_count={before_token_count} after_token_count={after_token_count}")
|
||||
|
||||
if not history_formatted_str:
|
||||
logger.warning(f"No history to summarize. messages={messages}")
|
||||
return ""
|
||||
|
||||
agent = ReActAgent(
|
||||
name="reme_summarizer",
|
||||
model=self.as_llm,
|
||||
sys_prompt="You are a helpful assistant.",
|
||||
formatter=self.as_llm_formatter,
|
||||
toolkit=self.toolkit,
|
||||
)
|
||||
|
||||
user_message: str = f"<conversation>\n{history_formatted_str}\n</conversation>\n" + self.prompt_format(
|
||||
"user_message",
|
||||
date=datetime.datetime.now().strftime("%Y-%m-%d"),
|
||||
working_dir=self.working_dir,
|
||||
memory_dir=self.memory_dir,
|
||||
)
|
||||
|
||||
summary_msg: Msg = await agent.reply(
|
||||
Msg(
|
||||
name="reme",
|
||||
role="user",
|
||||
content=user_message,
|
||||
),
|
||||
)
|
||||
|
||||
history_summary: str = summary_msg.get_text_content()
|
||||
logger.info(f"Summarizer Result:\n{history_summary}")
|
||||
return history_summary
|
||||
50
reme/memory/file_based/components/summarizer.yaml
Normal file
50
reme/memory/file_based/components/summarizer.yaml
Normal file
|
|
@ -0,0 +1,50 @@
|
|||
user_message: |
|
||||
Memory Pre-compression Flush Cycle Initiated
|
||||
The current session is about to enter the automatic compression phase. Please capture persistent memory and write it to disk.
|
||||
|
||||
Current date: {date}
|
||||
Working directory: {working_dir}
|
||||
|
||||
Immediately store persistent memory to: {memory_dir}/YYYY-MM-DD.md
|
||||
|
||||
Workflow:
|
||||
1. First, `read` {memory_dir}/YYYY-MM-DD.md (if the file doesn’t exist, an error message will be returned).
|
||||
2. Intelligently merge new information with existing content (skip merging if the file doesn’t exist):
|
||||
- Avoid duplicating already recorded information
|
||||
- Enrich existing entries with new details where relevant
|
||||
- Maintain chronological order wherever applicable
|
||||
3. Write the updated content:
|
||||
- Prefer using `edit` to update specific sections when possible
|
||||
- Use `write` to overwrite the entire file only if substantial restructuring is required
|
||||
|
||||
Principles:
|
||||
- Always preserve timestamps and any date/time-related context
|
||||
- Add only genuinely new or meaningfully enriching information
|
||||
- Keep entries concise yet complete
|
||||
- If there’s nothing to store, respond with [SILENT]
|
||||
|
||||
|
||||
user_message_zh: |
|
||||
预压缩内存刷新轮次。
|
||||
当前会话即将进入自动压缩阶段;请将持久化记忆捕获并写入磁盘。
|
||||
|
||||
当前日期:{date}
|
||||
工作目录:{working_dir}
|
||||
|
||||
立即存储持久化记忆(使用路径 {memory_dir}/YYYY-MM-DD.md)。
|
||||
|
||||
工作流程:
|
||||
1. 先 `read` {memory_dir}/YYYY-MM-DD.md(如文件不存在,会返回错误提示)
|
||||
2. 智能合并新信息与现有内容(若文件不存在则跳过合并):
|
||||
- 避免重复已记录的信息
|
||||
- 在相关时丰富现有条目的新细节
|
||||
- 在适用时保持时间顺序
|
||||
3. 写入更新后的内容:
|
||||
- 尽可能使用 `edit` 更新特定部分
|
||||
- 如需大幅重构则使用 `write` 覆盖整个文件
|
||||
|
||||
原则:
|
||||
- 始终保留时间戳、日期和时间相关上下文
|
||||
- 仅添加真正新的或有丰富价值的信息
|
||||
- 保持条目简洁但完整
|
||||
- 若无内容可存储,请回复 [SILENT]
|
||||
105
reme/memory/file_based/components/tool_result_compactor.py
Normal file
105
reme/memory/file_based/components/tool_result_compactor.py
Normal file
|
|
@ -0,0 +1,105 @@
|
|||
"""Tool Result Compactor: truncate large tool results and save full content to files."""
|
||||
|
||||
import uuid
|
||||
from datetime import datetime, timedelta
|
||||
from pathlib import Path
|
||||
|
||||
from agentscope.message import Msg
|
||||
|
||||
from ....core.op import BaseOp
|
||||
from ....core.utils import get_std_logger
|
||||
from ....core.utils import truncate_text, is_truncated
|
||||
|
||||
logger = get_std_logger()
|
||||
|
||||
|
||||
class ToolResultCompactor(BaseOp):
|
||||
"""Truncate large tool_result outputs and save full content to files."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
tool_result_dir: str | Path,
|
||||
tool_result_threshold: int,
|
||||
retention_days: int = 7,
|
||||
**kwargs,
|
||||
):
|
||||
super().__init__(**kwargs)
|
||||
self.tool_result_dir = Path(tool_result_dir)
|
||||
self.tool_result_threshold = tool_result_threshold
|
||||
self.retention_days = retention_days
|
||||
|
||||
def _save_and_truncate(self, content: str, tool_name: str) -> str:
|
||||
"""Save full content to file and return truncated version with file reference."""
|
||||
if not content or is_truncated(content) or len(content) <= self.tool_result_threshold:
|
||||
return content
|
||||
|
||||
# Save full content
|
||||
self.tool_result_dir.mkdir(parents=True, exist_ok=True)
|
||||
file_path = self.tool_result_dir / f"{uuid.uuid4().hex}.txt"
|
||||
created_at = datetime.now().isoformat()
|
||||
|
||||
file_path.write_text(
|
||||
f"# tool_name: {tool_name}\n# created_at: {created_at}\n# ---\n{content}",
|
||||
encoding="utf-8",
|
||||
)
|
||||
logger.debug("Saved tool result to %s (len=%d)", file_path, len(content))
|
||||
|
||||
# Return truncated with file reference
|
||||
return f"{truncate_text(content, self.tool_result_threshold)}\n\n[Full content saved to: {file_path}]"
|
||||
|
||||
def _process_output(self, output: str | list[dict], tool_name: str) -> str | list[dict]:
|
||||
"""Process tool result output, truncating if necessary."""
|
||||
if isinstance(output, str):
|
||||
return self._save_and_truncate(output, tool_name)
|
||||
|
||||
if isinstance(output, list):
|
||||
return [
|
||||
(
|
||||
{**b, "text": self._save_and_truncate(b.get("text", ""), tool_name)}
|
||||
if isinstance(b, dict) and b.get("type") == "text"
|
||||
else b
|
||||
)
|
||||
for b in output
|
||||
]
|
||||
return output
|
||||
|
||||
async def execute(self) -> list[Msg]:
|
||||
"""Process all messages, truncating large tool results."""
|
||||
messages: list[Msg] = self.context.get("messages", [])
|
||||
if not messages:
|
||||
return messages
|
||||
|
||||
for msg in messages:
|
||||
if not isinstance(msg.content, list):
|
||||
continue
|
||||
|
||||
for block in msg.content:
|
||||
if isinstance(block, dict) and block.get("type") == "tool_result":
|
||||
output = block.get("output")
|
||||
if output:
|
||||
block["output"] = self._process_output(output, block.get("name", "unknown"))
|
||||
|
||||
return messages
|
||||
|
||||
def cleanup_expired_files(self) -> int:
|
||||
"""Clean up files older than retention_days."""
|
||||
if not self.tool_result_dir.exists():
|
||||
return 0
|
||||
|
||||
cutoff = datetime.now() - timedelta(days=self.retention_days)
|
||||
deleted = 0
|
||||
|
||||
for fp in self.tool_result_dir.glob("*.txt"):
|
||||
try:
|
||||
for line in fp.read_text(encoding="utf-8").splitlines()[:3]:
|
||||
if line.startswith("# created_at:"):
|
||||
if datetime.fromisoformat(line.split(":", 1)[1].strip()) < cutoff:
|
||||
fp.unlink()
|
||||
deleted += 1
|
||||
break
|
||||
except Exception as e:
|
||||
logger.warning("Failed to process %s: %s", fp, e)
|
||||
|
||||
if deleted:
|
||||
logger.info("Cleaned up %d expired files", deleted)
|
||||
return deleted
|
||||
197
reme/memory/file_based/reme_in_memory_memory.py
Normal file
197
reme/memory/file_based/reme_in_memory_memory.py
Normal file
|
|
@ -0,0 +1,197 @@
|
|||
"""Custom memory implementation with bugfixes and extensions."""
|
||||
|
||||
from agentscope.agent._react_agent import _MemoryMark # noqa
|
||||
from agentscope.memory import InMemoryMemory
|
||||
from agentscope.message import Msg
|
||||
from agentscope.token import HuggingFaceTokenCounter
|
||||
|
||||
from .utils import AsMsgHandler
|
||||
from ...core.utils import get_std_logger
|
||||
|
||||
logger = get_std_logger()
|
||||
|
||||
|
||||
class ReMeInMemoryMemory(InMemoryMemory):
|
||||
"""Extended InMemoryMemory with bugfixes and summary support."""
|
||||
|
||||
def __init__(self, token_counter: HuggingFaceTokenCounter):
|
||||
super().__init__()
|
||||
self._token_counter: HuggingFaceTokenCounter = token_counter
|
||||
self._msg_handler: AsMsgHandler = AsMsgHandler(token_counter)
|
||||
|
||||
async def get_memory(
|
||||
self,
|
||||
mark: str | None = None,
|
||||
exclude_mark: str | None = _MemoryMark.COMPRESSED,
|
||||
prepend_summary: bool = True,
|
||||
**_kwargs,
|
||||
) -> list[Msg]:
|
||||
"""Get the messages from the memory by mark (if provided).
|
||||
|
||||
Args:
|
||||
mark: Optional mark to filter messages
|
||||
exclude_mark: Optional mark to exclude messages
|
||||
prepend_summary: Whether to prepend compressed summary
|
||||
**_kwargs: Additional keyword arguments (ignored)
|
||||
|
||||
Returns:
|
||||
List of filtered messages
|
||||
"""
|
||||
if not (mark is None or isinstance(mark, str)):
|
||||
raise TypeError(f"The mark should be a string or None, but got {type(mark)}.")
|
||||
|
||||
if not (exclude_mark is None or isinstance(exclude_mark, str)):
|
||||
raise TypeError(f"The exclude_mark should be a string or None, but got {type(exclude_mark)}.")
|
||||
|
||||
# Filter messages based on mark
|
||||
filtered_content = [(msg, marks) for msg, marks in self.content if mark is None or mark in marks]
|
||||
|
||||
# Further filter messages based on exclude_mark
|
||||
if exclude_mark is not None:
|
||||
filtered_content = [(msg, marks) for msg, marks in filtered_content if exclude_mark not in marks]
|
||||
|
||||
if prepend_summary and self._compressed_summary:
|
||||
previous_summary = f"""
|
||||
<previous-summary>
|
||||
{self._compressed_summary}
|
||||
</previous-summary>
|
||||
The above is a summary of our previous conversation.
|
||||
Use it as context to maintain continuity.
|
||||
""".strip()
|
||||
|
||||
return [
|
||||
Msg(
|
||||
"user",
|
||||
previous_summary,
|
||||
"user",
|
||||
),
|
||||
*[msg for msg, _ in filtered_content],
|
||||
]
|
||||
|
||||
return [msg for msg, _ in filtered_content]
|
||||
|
||||
def get_compressed_summary(self) -> str:
|
||||
"""Get the compressed summary of the memory."""
|
||||
return self._compressed_summary
|
||||
|
||||
def state_dict(self) -> dict:
|
||||
"""Get the state dictionary for serialization."""
|
||||
return {
|
||||
"content": [[msg.to_dict(), marks] for msg, marks in self.content],
|
||||
"_compressed_summary": self._compressed_summary,
|
||||
}
|
||||
|
||||
# pylint: disable=attribute-defined-outside-init
|
||||
def load_state_dict(self, state_dict: dict, strict: bool = True) -> None:
|
||||
"""Load the state dictionary for deserialization."""
|
||||
if strict and "content" not in state_dict:
|
||||
raise KeyError("The state_dict does not contain 'content' key required for InMemoryMemory.")
|
||||
|
||||
self.content = [] # pylint: disable=attribute-defined-outside-init
|
||||
for item in state_dict.get("content", []):
|
||||
if isinstance(item, (tuple, list)) and len(item) == 2:
|
||||
msg_dict, marks = item
|
||||
msg = Msg.from_dict(msg_dict)
|
||||
self.content.append((msg, marks))
|
||||
|
||||
elif isinstance(item, dict):
|
||||
# For compatibility with older versions
|
||||
msg = Msg.from_dict(item)
|
||||
self.content.append((msg, []))
|
||||
|
||||
else:
|
||||
raise ValueError("Invalid item format in state_dict for InMemoryMemory.")
|
||||
|
||||
self._compressed_summary = state_dict.get("_compressed_summary", "")
|
||||
|
||||
async def mark_messages_compressed(self, messages: list[Msg]) -> int:
|
||||
"""Mark messages as compressed and return count."""
|
||||
return await self.update_messages_mark(
|
||||
new_mark=_MemoryMark.COMPRESSED,
|
||||
msg_ids=[msg.id for msg in messages],
|
||||
)
|
||||
|
||||
def clear_compressed_summary(self):
|
||||
"""Clear the compressed summary."""
|
||||
self._compressed_summary = "" # pylint: disable=attribute-defined-outside-init
|
||||
|
||||
def clear_content(self):
|
||||
"""Clear the content."""
|
||||
self.content.clear()
|
||||
|
||||
async def estimate_tokens(self, max_input_length: int) -> dict:
|
||||
"""Estimate token usage for current memory.
|
||||
|
||||
Args:
|
||||
max_input_length: Max input length for context usage calculation.
|
||||
|
||||
Returns:
|
||||
Dict containing detailed token statistics:
|
||||
- total_messages: Number of messages
|
||||
- compressed_summary_tokens: Tokens in compressed summary
|
||||
- messages_tokens: Tokens in messages
|
||||
- estimated_tokens: Total estimated tokens
|
||||
- max_input_length: Max input length from config
|
||||
- context_usage_ratio: Usage percentage
|
||||
- messages_detail: List of per-message AsMsgStat objects
|
||||
"""
|
||||
messages = await self.get_memory(
|
||||
exclude_mark=_MemoryMark.COMPRESSED,
|
||||
prepend_summary=False,
|
||||
)
|
||||
|
||||
compressed_summary = self.get_compressed_summary()
|
||||
compressed_summary_tokens = self._msg_handler.count_str_token(compressed_summary)
|
||||
|
||||
# Build per-message token details using AsMsgHandler
|
||||
messages_detail = [self._msg_handler.stat_message(msg) for msg in messages]
|
||||
|
||||
# Calculate total message tokens from stats
|
||||
messages_tokens = sum(stat.total_tokens for stat in messages_detail)
|
||||
estimated_tokens = messages_tokens + compressed_summary_tokens
|
||||
|
||||
# Calculate context usage ratio
|
||||
context_usage_ratio = (estimated_tokens / max_input_length * 100) if max_input_length > 0 else 0
|
||||
|
||||
return {
|
||||
"total_messages": len(messages),
|
||||
"compressed_summary_tokens": compressed_summary_tokens,
|
||||
"messages_tokens": messages_tokens,
|
||||
"estimated_tokens": estimated_tokens,
|
||||
"max_input_length": max_input_length,
|
||||
"context_usage_ratio": context_usage_ratio,
|
||||
"messages_detail": messages_detail,
|
||||
}
|
||||
|
||||
async def get_history_str(self, max_input_length: int) -> str:
|
||||
"""Get formatted history string similar to /history command output.
|
||||
|
||||
Args:
|
||||
max_input_length: Max input length for context usage calculation.
|
||||
|
||||
Returns:
|
||||
Formatted string containing conversation history details
|
||||
"""
|
||||
stats = await self.estimate_tokens(max_input_length)
|
||||
|
||||
lines = []
|
||||
for i, msg_stat in enumerate(stats["messages_detail"], 1):
|
||||
blocks_info = ""
|
||||
if msg_stat.content:
|
||||
block_strs = [f"{b.block_type}(tokens={b.token_count})" for b in msg_stat.content]
|
||||
blocks_info = f"\n content: [{', '.join(block_strs)}]"
|
||||
|
||||
lines.append(
|
||||
f"[{i}] **{msg_stat.role}** "
|
||||
f"(total_tokens={msg_stat.total_tokens})"
|
||||
f"{blocks_info}\n preview: {msg_stat.preview}",
|
||||
)
|
||||
|
||||
return (
|
||||
f"**Conversation History**\n\n"
|
||||
f"- Total messages: {stats['total_messages']}\n"
|
||||
f"- Estimated tokens: {stats['estimated_tokens']}\n"
|
||||
f"- Max input length: {stats['max_input_length']}\n"
|
||||
f"- Context usage: {stats['context_usage_ratio']:.1f}%\n"
|
||||
f"- Compressed summary tokens: {stats['compressed_summary_tokens']}\n\n" + "\n\n".join(lines)
|
||||
)
|
||||
13
reme/memory/file_based/tools/__init__.py
Normal file
13
reme/memory/file_based/tools/__init__.py
Normal file
|
|
@ -0,0 +1,13 @@
|
|||
"""File-based memory tool implementations."""
|
||||
|
||||
from .file_io import FileIO
|
||||
from .memory_get import MemoryGet
|
||||
from .memory_search import MemorySearch
|
||||
from .shell import Shell
|
||||
|
||||
__all__ = [
|
||||
"FileIO",
|
||||
"MemoryGet",
|
||||
"MemorySearch",
|
||||
"Shell",
|
||||
]
|
||||
256
reme/memory/file_based/tools/file_io.py
Normal file
256
reme/memory/file_based/tools/file_io.py
Normal file
|
|
@ -0,0 +1,256 @@
|
|||
"""File I/O operations with a configurable working directory."""
|
||||
|
||||
import os
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
|
||||
from agentscope.message import TextBlock
|
||||
from agentscope.tool import ToolResponse
|
||||
|
||||
from ..utils import DEFAULT_MAX_BYTES, read_file_safe, truncate_output
|
||||
|
||||
|
||||
class FileIO:
|
||||
"""File I/O operations with a configurable working directory."""
|
||||
|
||||
def __init__(self, working_dir: str | Path):
|
||||
"""Initialize FileIO with a working directory.
|
||||
|
||||
Args:
|
||||
working_dir (`str`):
|
||||
The working directory for resolving relative paths.
|
||||
"""
|
||||
self.working_dir = Path(working_dir)
|
||||
|
||||
def _resolve_file_path(self, file_path: str) -> str:
|
||||
"""Resolve file path: use absolute path as-is,
|
||||
resolve relative path from working_dir.
|
||||
|
||||
Args:
|
||||
file_path: The input file path (absolute or relative).
|
||||
|
||||
Returns:
|
||||
The resolved absolute file path as string.
|
||||
"""
|
||||
path = Path(file_path)
|
||||
if path.is_absolute():
|
||||
return str(path)
|
||||
else:
|
||||
return str(self.working_dir / file_path)
|
||||
|
||||
async def read( # pylint: disable=too-many-return-statements
|
||||
self,
|
||||
file_path: str,
|
||||
start_line: Optional[int] = None,
|
||||
end_line: Optional[int] = None,
|
||||
) -> ToolResponse:
|
||||
"""Read a file. Relative paths resolve from working_dir.
|
||||
|
||||
Use start_line/end_line to read a specific line range (output includes
|
||||
line numbers). Omit both to read the full file.
|
||||
|
||||
Args:
|
||||
file_path (`str`):
|
||||
Path to the file.
|
||||
start_line (`int`, optional):
|
||||
First line to read (1-based, inclusive).
|
||||
end_line (`int`, optional):
|
||||
Last line to read (1-based, inclusive).
|
||||
"""
|
||||
file_path = self._resolve_file_path(file_path)
|
||||
|
||||
if not os.path.exists(file_path):
|
||||
return ToolResponse(
|
||||
content=[
|
||||
TextBlock(
|
||||
type="text",
|
||||
text=f"Error: The file {file_path} does not exist.",
|
||||
),
|
||||
],
|
||||
)
|
||||
|
||||
if not os.path.isfile(file_path):
|
||||
return ToolResponse(
|
||||
content=[
|
||||
TextBlock(
|
||||
type="text",
|
||||
text=f"Error: The path {file_path} is not a file.",
|
||||
),
|
||||
],
|
||||
)
|
||||
|
||||
try:
|
||||
content = read_file_safe(file_path)
|
||||
all_lines = content.split("\n")
|
||||
total = len(all_lines)
|
||||
|
||||
# Determine read range
|
||||
s = max(1, start_line if start_line is not None else 1)
|
||||
e = min(total, end_line if end_line is not None else total)
|
||||
|
||||
if s > total:
|
||||
return ToolResponse(
|
||||
content=[
|
||||
TextBlock(
|
||||
type="text",
|
||||
text=f"Error: start_line {s} exceeds file length ({total} lines).",
|
||||
),
|
||||
],
|
||||
)
|
||||
|
||||
if s > e:
|
||||
return ToolResponse(
|
||||
content=[
|
||||
TextBlock(
|
||||
type="text",
|
||||
text=f"Error: start_line ({s}) > end_line ({e}).",
|
||||
),
|
||||
],
|
||||
)
|
||||
|
||||
# Extract selected lines
|
||||
selected_content = "\n".join(all_lines[s - 1 : e])
|
||||
|
||||
# Apply smart truncation (keep head for file reading)
|
||||
truncated, was_truncated, output_lines, reason = truncate_output(selected_content, keep="head")
|
||||
|
||||
# Build response with truncation hints
|
||||
if was_truncated:
|
||||
end_display = s + output_lines - 1
|
||||
next_line = end_display + 1
|
||||
if reason == "lines":
|
||||
hint = f"\n\n[Lines {s}-{end_display} of {total}. Use start_line={next_line} to continue.]"
|
||||
else:
|
||||
hint = (
|
||||
f"\n\n[Lines {s}-{end_display} of {total} ({DEFAULT_MAX_BYTES // 1024}KB limit). "
|
||||
f"Use start_line={next_line} to continue.]"
|
||||
)
|
||||
text = truncated + hint
|
||||
elif e < total:
|
||||
remaining = total - e
|
||||
text = (
|
||||
f"{file_path} (lines {s}-{e} of {total})\n{truncated}\n\n[{remaining} more lines. "
|
||||
f"Use start_line={e + 1} to continue.]"
|
||||
)
|
||||
else:
|
||||
text = truncated
|
||||
|
||||
return ToolResponse(
|
||||
content=[TextBlock(type="text", text=text)],
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
return ToolResponse(
|
||||
content=[
|
||||
TextBlock(
|
||||
type="text",
|
||||
text=f"Error: Read file failed due to \n{e}",
|
||||
),
|
||||
],
|
||||
)
|
||||
|
||||
async def write(
|
||||
self,
|
||||
file_path: str,
|
||||
content: str,
|
||||
) -> ToolResponse:
|
||||
"""Create or overwrite a file. Relative paths resolve from working_dir.
|
||||
|
||||
Args:
|
||||
file_path (`str`):
|
||||
Path to the file.
|
||||
content (`str`):
|
||||
Content to write.
|
||||
"""
|
||||
if not file_path:
|
||||
return ToolResponse(
|
||||
content=[
|
||||
TextBlock(
|
||||
type="text",
|
||||
text="Error: No `file_path` provide.",
|
||||
),
|
||||
],
|
||||
)
|
||||
|
||||
file_path = self._resolve_file_path(file_path)
|
||||
|
||||
try:
|
||||
with open(file_path, "w", encoding="utf-8") as file:
|
||||
file.write(content)
|
||||
return ToolResponse(
|
||||
content=[
|
||||
TextBlock(
|
||||
type="text",
|
||||
text=f"Wrote {len(content)} bytes to {file_path}.",
|
||||
),
|
||||
],
|
||||
)
|
||||
except Exception as e:
|
||||
return ToolResponse(
|
||||
content=[
|
||||
TextBlock(
|
||||
type="text",
|
||||
text=f"Error: Write file failed due to \n{e}",
|
||||
),
|
||||
],
|
||||
)
|
||||
|
||||
async def edit(
|
||||
self,
|
||||
file_path: str,
|
||||
old_text: str,
|
||||
new_text: str,
|
||||
) -> ToolResponse:
|
||||
"""Find-and-replace text in a file. All occurrences of old_text are
|
||||
replaced with new_text. Relative paths resolve from working_dir.
|
||||
|
||||
Args:
|
||||
file_path (`str`):
|
||||
Path to the file.
|
||||
old_text (`str`):
|
||||
Exact text to find.
|
||||
new_text (`str`):
|
||||
Replacement text.
|
||||
"""
|
||||
response = await self.read(file_path=file_path)
|
||||
if response.content and len(response.content) > 0:
|
||||
error_text = response.content[0].get("text", "")
|
||||
if error_text.startswith("Error:"):
|
||||
return response
|
||||
if not response.content or len(response.content) == 0:
|
||||
return ToolResponse(
|
||||
content=[
|
||||
TextBlock(
|
||||
type="text",
|
||||
text=f"Error: Failed to read file {file_path}.",
|
||||
),
|
||||
],
|
||||
)
|
||||
|
||||
content = response.content[0].get("text", "")
|
||||
if old_text not in content:
|
||||
return ToolResponse(
|
||||
content=[
|
||||
TextBlock(
|
||||
type="text",
|
||||
text=f"Error: The text to replace was not found in {file_path}.",
|
||||
),
|
||||
],
|
||||
)
|
||||
|
||||
new_content = content.replace(old_text, new_text)
|
||||
write_response = await self.write(file_path=file_path, content=new_content)
|
||||
|
||||
if write_response.content and len(write_response.content) > 0:
|
||||
write_text = write_response.content[0].get("text", "")
|
||||
if write_text.startswith("Error:"):
|
||||
return write_response
|
||||
|
||||
return ToolResponse(
|
||||
content=[
|
||||
TextBlock(
|
||||
type="text",
|
||||
text=f"Successfully replaced text in {file_path}.",
|
||||
),
|
||||
],
|
||||
)
|
||||
229
reme/memory/file_based/tools/shell.py
Normal file
229
reme/memory/file_based/tools/shell.py
Normal file
|
|
@ -0,0 +1,229 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
# flake8: noqa: E501
|
||||
# pylint: disable=line-too-long
|
||||
"""The shell command tool."""
|
||||
|
||||
import asyncio
|
||||
import locale
|
||||
import subprocess
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
from agentscope.message import TextBlock
|
||||
from agentscope.tool import ToolResponse
|
||||
|
||||
from ..utils import truncate_shell_output
|
||||
|
||||
|
||||
def _execute_subprocess_sync(
|
||||
cmd: str,
|
||||
cwd: str,
|
||||
timeout: int,
|
||||
) -> tuple[int, str, str]:
|
||||
"""Execute subprocess synchronously in a thread.
|
||||
|
||||
This function runs in a separate thread to avoid Windows asyncio
|
||||
subprocess limitations.
|
||||
|
||||
Args:
|
||||
cmd (`str`):
|
||||
The shell command to execute.
|
||||
cwd (`str`):
|
||||
The working directory for the command execution.
|
||||
timeout (`int`):
|
||||
The maximum time (in seconds) allowed for the command to run.
|
||||
|
||||
Returns:
|
||||
`tuple[int, str, str]`:
|
||||
A tuple containing the return code, standard output, and
|
||||
standard error of the executed command. If timeout occurs, the
|
||||
return code will be -1 and stderr will contain timeout information.
|
||||
"""
|
||||
try:
|
||||
result = subprocess.run(
|
||||
cmd,
|
||||
shell=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
cwd=cwd,
|
||||
timeout=timeout,
|
||||
encoding=locale.getpreferredencoding(False) or "utf-8",
|
||||
errors="replace",
|
||||
check=True,
|
||||
)
|
||||
return (
|
||||
result.returncode,
|
||||
result.stdout.strip("\n"),
|
||||
result.stderr.strip("\n"),
|
||||
)
|
||||
except subprocess.TimeoutExpired:
|
||||
return (
|
||||
-1,
|
||||
"",
|
||||
f"Command execution exceeded the timeout of {timeout} seconds.",
|
||||
)
|
||||
except Exception as e:
|
||||
return -1, "", str(e)
|
||||
|
||||
|
||||
class Shell:
|
||||
"""Shell command execution with a configurable working directory."""
|
||||
|
||||
def __init__(self, working_dir: str | Path):
|
||||
"""Initialize Shell with a working directory.
|
||||
|
||||
Args:
|
||||
working_dir (`str | Path`):
|
||||
The working directory for command execution.
|
||||
"""
|
||||
self.working_dir = Path(working_dir)
|
||||
|
||||
# pylint: disable=too-many-branches, too-many-statements
|
||||
async def execute_shell_command(
|
||||
self,
|
||||
command: str,
|
||||
timeout: int = 60,
|
||||
) -> ToolResponse:
|
||||
"""Execute given command and return the return code, standard output and
|
||||
error within <returncode></returncode>, <stdout></stdout> and
|
||||
<stderr></stderr> tags.
|
||||
|
||||
Args:
|
||||
command (`str`):
|
||||
The shell command to execute.
|
||||
timeout (`int`, defaults to `60`):
|
||||
The maximum time (in seconds) allowed for the command to run.
|
||||
Default is 60 seconds.
|
||||
|
||||
Returns:
|
||||
`ToolResponse`:
|
||||
The tool response containing the return code, standard output, and
|
||||
standard error of the executed command. If timeout occurs, the
|
||||
return code will be -1 and stderr will contain timeout information.
|
||||
"""
|
||||
|
||||
cmd = (command or "").strip()
|
||||
|
||||
# Set working directory
|
||||
working_dir = self.working_dir
|
||||
|
||||
try:
|
||||
if sys.platform == "win32":
|
||||
# Windows: use thread pool to avoid asyncio subprocess limitations
|
||||
returncode, stdout_str, stderr_str = await asyncio.to_thread(
|
||||
_execute_subprocess_sync,
|
||||
cmd,
|
||||
str(working_dir),
|
||||
timeout,
|
||||
)
|
||||
else:
|
||||
proc = await asyncio.create_subprocess_shell(
|
||||
cmd,
|
||||
stdout=asyncio.subprocess.PIPE,
|
||||
stderr=asyncio.subprocess.PIPE,
|
||||
bufsize=0,
|
||||
cwd=str(working_dir),
|
||||
)
|
||||
|
||||
try:
|
||||
# Apply timeout to communicate directly; wait()+communicate()
|
||||
# can hang if descendants keep stdout/stderr pipes open.
|
||||
stdout, stderr = await asyncio.wait_for(
|
||||
proc.communicate(),
|
||||
timeout=timeout,
|
||||
)
|
||||
encoding = locale.getpreferredencoding(False) or "utf-8"
|
||||
stdout_str = stdout.decode(encoding, errors="replace").strip(
|
||||
"\n",
|
||||
)
|
||||
stderr_str = stderr.decode(encoding, errors="replace").strip(
|
||||
"\n",
|
||||
)
|
||||
returncode = proc.returncode
|
||||
|
||||
except asyncio.TimeoutError:
|
||||
# Handle timeout
|
||||
stderr_suffix = (
|
||||
f"⚠️ TimeoutError: The command execution exceeded "
|
||||
f"the timeout of {timeout} seconds. "
|
||||
f"Please consider increasing the timeout value if this command "
|
||||
f"requires more time to complete."
|
||||
)
|
||||
returncode = -1
|
||||
try:
|
||||
proc.terminate()
|
||||
# Wait a bit for graceful termination
|
||||
try:
|
||||
await asyncio.wait_for(proc.wait(), timeout=1)
|
||||
except asyncio.TimeoutError:
|
||||
# Force kill if graceful termination fails
|
||||
proc.kill()
|
||||
await proc.wait()
|
||||
|
||||
# Avoid hanging forever while draining pipes after timeout.
|
||||
try:
|
||||
stdout, stderr = await asyncio.wait_for(
|
||||
proc.communicate(),
|
||||
timeout=1,
|
||||
)
|
||||
except asyncio.TimeoutError:
|
||||
stdout, stderr = b"", b""
|
||||
encoding = locale.getpreferredencoding(False) or "utf-8"
|
||||
stdout_str = stdout.decode(
|
||||
encoding,
|
||||
errors="replace",
|
||||
).strip(
|
||||
"\n",
|
||||
)
|
||||
stderr_str = stderr.decode(
|
||||
encoding,
|
||||
errors="replace",
|
||||
).strip(
|
||||
"\n",
|
||||
)
|
||||
if stderr_str:
|
||||
stderr_str += f"\n{stderr_suffix}"
|
||||
else:
|
||||
stderr_str = stderr_suffix
|
||||
except ProcessLookupError:
|
||||
stdout_str = ""
|
||||
stderr_str = stderr_suffix
|
||||
|
||||
# Apply output truncation
|
||||
stdout_str = truncate_shell_output(stdout_str)
|
||||
stderr_str = truncate_shell_output(stderr_str)
|
||||
|
||||
# Format the response in a human-friendly way
|
||||
if returncode == 0:
|
||||
# Success case: just show the output
|
||||
if stdout_str:
|
||||
response_text = stdout_str
|
||||
else:
|
||||
response_text = "Command executed successfully (no output)."
|
||||
else:
|
||||
# Error case: show detailed information
|
||||
response_parts = [f"Command failed with exit code {returncode}."]
|
||||
if stdout_str:
|
||||
response_parts.append(f"\n[stdout]\n{stdout_str}")
|
||||
if stderr_str:
|
||||
response_parts.append(f"\n[stderr]\n{stderr_str}")
|
||||
response_text = "".join(response_parts)
|
||||
|
||||
return ToolResponse(
|
||||
content=[
|
||||
TextBlock(
|
||||
type="text",
|
||||
text=response_text,
|
||||
),
|
||||
],
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
return ToolResponse(
|
||||
content=[
|
||||
TextBlock(
|
||||
type="text",
|
||||
text=f"Error: Shell command execution failed due to \n{e}",
|
||||
),
|
||||
],
|
||||
)
|
||||
13
reme/memory/file_based/utils/__init__.py
Normal file
13
reme/memory/file_based/utils/__init__.py
Normal file
|
|
@ -0,0 +1,13 @@
|
|||
"""utils"""
|
||||
|
||||
from .as_msg_handler import AsMsgHandler
|
||||
from .file_utils import truncate_output, truncate_shell_output, read_file_safe, DEFAULT_MAX_BYTES, DEFAULT_MAX_LINES
|
||||
|
||||
__all__ = [
|
||||
"AsMsgHandler",
|
||||
"truncate_output",
|
||||
"truncate_shell_output",
|
||||
"read_file_safe",
|
||||
"DEFAULT_MAX_BYTES",
|
||||
"DEFAULT_MAX_LINES",
|
||||
]
|
||||
425
reme/memory/file_based/utils/as_msg_handler.py
Normal file
425
reme/memory/file_based/utils/as_msg_handler.py
Normal file
|
|
@ -0,0 +1,425 @@
|
|||
"""Handler for AgentScope message processing, token counting, and context management."""
|
||||
|
||||
import json
|
||||
|
||||
from agentscope.message import Msg
|
||||
from agentscope.token import HuggingFaceTokenCounter
|
||||
|
||||
from ....core.schema import AsMsgStat, AsBlockStat
|
||||
from ....core.utils import get_std_logger
|
||||
|
||||
logger = get_std_logger()
|
||||
|
||||
|
||||
class AsMsgHandler:
|
||||
"""Handles token counting, formatting, and context compaction for AgentScope messages."""
|
||||
|
||||
def __init__(self, token_counter: HuggingFaceTokenCounter):
|
||||
self._token_counter = token_counter
|
||||
|
||||
def count_str_token(self, text: str) -> int:
|
||||
"""Count tokens in a string.
|
||||
|
||||
Args:
|
||||
text: The text to count tokens for.
|
||||
|
||||
Returns:
|
||||
The number of tokens in the text.
|
||||
"""
|
||||
if not text:
|
||||
return 0
|
||||
|
||||
try:
|
||||
token_ids = self._token_counter.tokenizer.encode(text)
|
||||
token_count = len(token_ids)
|
||||
return token_count
|
||||
|
||||
except Exception as e:
|
||||
estimated_tokens = len(text.encode("utf-8")) // 4
|
||||
logger.warning(f"Failed to count string tokens: {text}, e={e}")
|
||||
return estimated_tokens
|
||||
|
||||
def _format_tool_result_output(self, output: str | list[dict]) -> tuple[str, int]:
|
||||
"""Convert tool result output to string."""
|
||||
if isinstance(output, str):
|
||||
return output, self.count_str_token(output)
|
||||
|
||||
textual_parts = []
|
||||
total_token_count = 0
|
||||
for block in output:
|
||||
try:
|
||||
if not isinstance(block, dict) or "type" not in block:
|
||||
logger.warning(
|
||||
"Invalid block: %s, expected a dict with 'type' key, skipped.",
|
||||
block,
|
||||
)
|
||||
continue
|
||||
|
||||
block_type = block["type"]
|
||||
|
||||
if block_type == "text":
|
||||
textual_parts.append(block.get("text", ""))
|
||||
total_token_count += self.count_str_token(textual_parts[-1])
|
||||
|
||||
elif block_type in ["image", "audio", "video"]:
|
||||
source = block.get("source", {})
|
||||
if source.get("type") == "base64":
|
||||
data = source.get("data", "")
|
||||
total_token_count += len(data) // 4 if data else 10
|
||||
else:
|
||||
url = source.get("url", "")
|
||||
total_token_count += self.count_str_token(url) if url else 10
|
||||
textual_parts.append(f"[{block_type}] {url}")
|
||||
|
||||
elif block_type == "file":
|
||||
file_path = block.get("path", "") or block.get("url", "")
|
||||
file_name = block.get("name", file_path)
|
||||
textual_parts.append(f"[file] {file_name}: {file_path}")
|
||||
total_token_count += self.count_str_token(file_path)
|
||||
|
||||
else:
|
||||
logger.warning(
|
||||
"Unsupported block type '%s' in tool result, skipped.",
|
||||
block_type,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
logger.warning(
|
||||
"Failed to process block %s: %s, skipped.",
|
||||
block,
|
||||
e,
|
||||
)
|
||||
|
||||
return "\n".join(textual_parts), total_token_count
|
||||
|
||||
def stat_message(self, message: Msg) -> AsMsgStat:
|
||||
"""Analyze a message and generate block statistics."""
|
||||
blocks = []
|
||||
if isinstance(message.content, str):
|
||||
blocks.append(
|
||||
AsBlockStat(
|
||||
block_type="text",
|
||||
text=message.content,
|
||||
token_count=self.count_str_token(message.content),
|
||||
),
|
||||
)
|
||||
return AsMsgStat(
|
||||
name=message.name or message.role,
|
||||
role=message.role,
|
||||
content=blocks,
|
||||
timestamp=message.timestamp or "",
|
||||
metadata=message.metadata or {},
|
||||
)
|
||||
|
||||
if not isinstance(message.content, list):
|
||||
logger.warning(
|
||||
"Unexpected message.content type %s, expected str or list, returning empty stat.",
|
||||
type(message.content),
|
||||
)
|
||||
return AsMsgStat(
|
||||
name=message.name or message.role,
|
||||
role=message.role,
|
||||
content=blocks,
|
||||
timestamp=message.timestamp or "",
|
||||
metadata=message.metadata or {},
|
||||
)
|
||||
|
||||
for block in message.content:
|
||||
block_type = block.get("type", "unknown")
|
||||
|
||||
if block_type == "text":
|
||||
text = block.get("text", "")
|
||||
token_count = self.count_str_token(text)
|
||||
blocks.append(
|
||||
AsBlockStat(
|
||||
block_type=block_type,
|
||||
text=text,
|
||||
token_count=token_count,
|
||||
),
|
||||
)
|
||||
|
||||
elif block_type == "thinking":
|
||||
thinking = block.get("thinking", "")
|
||||
token_count = self.count_str_token(thinking)
|
||||
blocks.append(
|
||||
AsBlockStat(
|
||||
block_type=block_type,
|
||||
text=thinking,
|
||||
token_count=token_count,
|
||||
),
|
||||
)
|
||||
|
||||
elif block_type in ("image", "audio", "video"):
|
||||
source = block.get("source", {})
|
||||
url = source.get("url", "")
|
||||
if source.get("type") == "base64":
|
||||
data = source.get("data", "")
|
||||
token_count = len(data) // 4 if data else 10
|
||||
else:
|
||||
token_count = self.count_str_token(url) if url else 10
|
||||
blocks.append(
|
||||
AsBlockStat(
|
||||
block_type=block_type,
|
||||
text="",
|
||||
token_count=token_count,
|
||||
media_url=url,
|
||||
),
|
||||
)
|
||||
|
||||
elif block_type == "tool_use":
|
||||
tool_name = block.get("name", "")
|
||||
tool_input = block.get("input", "")
|
||||
try:
|
||||
input_str = json.dumps(tool_input, ensure_ascii=False)
|
||||
except (TypeError, ValueError):
|
||||
input_str = str(tool_input)
|
||||
token_count = self.count_str_token(tool_name + input_str)
|
||||
blocks.append(
|
||||
AsBlockStat(
|
||||
block_type=block_type,
|
||||
text="",
|
||||
token_count=token_count,
|
||||
tool_name=tool_name,
|
||||
tool_input=input_str,
|
||||
),
|
||||
)
|
||||
|
||||
elif block_type == "tool_result":
|
||||
tool_name = block.get("name", "")
|
||||
output = block.get("output", "")
|
||||
formatted_output, token_count = self._format_tool_result_output(output)
|
||||
blocks.append(
|
||||
AsBlockStat(
|
||||
block_type=block_type,
|
||||
text="",
|
||||
token_count=token_count,
|
||||
tool_name=tool_name,
|
||||
tool_output=formatted_output,
|
||||
),
|
||||
)
|
||||
|
||||
else:
|
||||
logger.warning("Unsupported block type %s, skipped.", block_type)
|
||||
|
||||
return AsMsgStat(
|
||||
name=message.name or message.role,
|
||||
role=message.role,
|
||||
content=blocks,
|
||||
timestamp=message.timestamp or "",
|
||||
metadata=message.metadata or {},
|
||||
)
|
||||
|
||||
def count_msgs_token(self, messages: list[Msg]) -> int:
|
||||
"""Count total token count of a list of messages."""
|
||||
return sum(self.stat_message(msg).total_tokens for msg in messages)
|
||||
|
||||
def format_msgs_to_str(
|
||||
self,
|
||||
messages: list[Msg],
|
||||
memory_compact_threshold: int,
|
||||
include_thinking: bool = False,
|
||||
) -> str:
|
||||
"""Format list of messages to a single formatted string.
|
||||
|
||||
Messages are processed in reverse order (newest first) and older
|
||||
messages are skipped when token count exceeds memory_compact_threshold.
|
||||
|
||||
Args:
|
||||
messages: List of Msg objects to format.
|
||||
memory_compact_threshold: Maximum token count before skipping older messages.
|
||||
include_thinking: Whether to include thinking blocks in output.
|
||||
"""
|
||||
if not messages:
|
||||
return ""
|
||||
|
||||
formatted_parts: list[str] = []
|
||||
total_token_count = 0
|
||||
|
||||
for i in range(len(messages) - 1, -1, -1):
|
||||
stat = self.stat_message(messages[i])
|
||||
formatted_content = stat.format(include_thinking=include_thinking)
|
||||
content_token_count = self.count_str_token(formatted_content)
|
||||
|
||||
is_latest = i == len(messages) - 1
|
||||
if not is_latest and total_token_count + content_token_count > memory_compact_threshold:
|
||||
logger.info(
|
||||
"Skipping older messages: adding %d tokens would exceed threshold %d (current: %d)",
|
||||
content_token_count,
|
||||
memory_compact_threshold,
|
||||
total_token_count,
|
||||
)
|
||||
break
|
||||
|
||||
if is_latest and content_token_count > memory_compact_threshold:
|
||||
logger.warning(
|
||||
"Latest message alone (%d tokens) exceeds threshold %d, including it anyway.",
|
||||
content_token_count,
|
||||
memory_compact_threshold,
|
||||
)
|
||||
|
||||
formatted_parts.append(formatted_content)
|
||||
total_token_count += content_token_count
|
||||
|
||||
formatted_parts.reverse()
|
||||
return "\n\n".join(formatted_parts)
|
||||
|
||||
@staticmethod
|
||||
def validate_tool_ids_alignment(messages: list[Msg]) -> bool:
|
||||
"""Check if tool_use_ids and tool_result_ids are properly aligned.
|
||||
|
||||
Args:
|
||||
messages: List of Msg objects to validate.
|
||||
|
||||
Returns:
|
||||
True if all tool_use ids have corresponding tool_result ids and vice versa.
|
||||
"""
|
||||
tool_use_ids: set[str] = set()
|
||||
tool_result_ids: set[str] = set()
|
||||
|
||||
for msg in messages:
|
||||
for block in msg.get_content_blocks("tool_use"):
|
||||
if tool_id := block.get("id"):
|
||||
tool_use_ids.add(tool_id)
|
||||
for block in msg.get_content_blocks("tool_result"):
|
||||
if tool_id := block.get("id"):
|
||||
tool_result_ids.add(tool_id)
|
||||
|
||||
return tool_use_ids == tool_result_ids
|
||||
|
||||
def context_check(
|
||||
self,
|
||||
messages: list[Msg],
|
||||
memory_compact_threshold: int,
|
||||
memory_compact_reserve: int,
|
||||
) -> tuple[list[Msg], list[Msg], bool]:
|
||||
"""Check if context exceeds threshold and split messages accordingly.
|
||||
|
||||
Only when total tokens exceed memory_compact_threshold, messages are split into
|
||||
messages_to_keep (within reserve limit) and messages_to_compact (older messages).
|
||||
|
||||
Args:
|
||||
messages: List of Msg objects to check.
|
||||
memory_compact_threshold: Maximum token count threshold to trigger compaction.
|
||||
memory_compact_reserve: Token limit for messages to keep.
|
||||
|
||||
Returns:
|
||||
A tuple of (messages_to_compact, messages_to_keep, tools_aligned):
|
||||
- messages_to_compact: Older messages that exceed reserve limit
|
||||
- messages_to_keep: Recent messages within the reserve limit
|
||||
- tools_aligned: Whether tool_use and tool_result ids are aligned in messages_to_keep
|
||||
"""
|
||||
if not messages:
|
||||
return [], [], True
|
||||
|
||||
# Calculate total tokens and stats for all messages
|
||||
msg_stats: list[tuple[Msg, AsMsgStat]] = []
|
||||
total_tokens = 0
|
||||
for msg in messages:
|
||||
stat = self.stat_message(msg)
|
||||
msg_stats.append((msg, stat))
|
||||
total_tokens += stat.total_tokens
|
||||
|
||||
# If total tokens don't exceed threshold, no split needed
|
||||
if total_tokens < memory_compact_threshold:
|
||||
return [], messages, True
|
||||
|
||||
# Collect all tool_use ids and their message indices
|
||||
# tool_use_id -> message index
|
||||
tool_use_locations: dict[str, int] = {}
|
||||
# tool_result_id -> message index
|
||||
tool_result_locations: dict[str, int] = {}
|
||||
|
||||
for idx, (msg, _) in enumerate(msg_stats):
|
||||
for block in msg.get_content_blocks("tool_use"):
|
||||
tool_id = block.get("id", "")
|
||||
if tool_id:
|
||||
tool_use_locations[tool_id] = idx
|
||||
|
||||
for block in msg.get_content_blocks("tool_result"):
|
||||
tool_id = block.get("id", "")
|
||||
if tool_id:
|
||||
tool_result_locations[tool_id] = idx
|
||||
|
||||
# Iterate from the end, accumulating messages to keep within reserve limit
|
||||
keep_indices: set[int] = set()
|
||||
accumulated_tokens = 0
|
||||
|
||||
for i in range(len(msg_stats) - 1, -1, -1):
|
||||
# Skip messages already added as tool_use dependencies to avoid double-counting tokens
|
||||
if i in keep_indices:
|
||||
continue
|
||||
|
||||
msg, stat = msg_stats[i]
|
||||
|
||||
# Check if adding this message would exceed reserve limit
|
||||
if accumulated_tokens + stat.total_tokens > memory_compact_reserve:
|
||||
logger.info(
|
||||
"Context check: adding message %d with %d tokens would exceed reserve %d (current: %d)",
|
||||
i,
|
||||
stat.total_tokens,
|
||||
memory_compact_reserve,
|
||||
accumulated_tokens,
|
||||
)
|
||||
break
|
||||
|
||||
# Check tool_result dependencies - if this message has tool_result,
|
||||
# we need to ensure the corresponding tool_use is also included
|
||||
tool_result_ids = [
|
||||
block.get("id", "") for block in msg.get_content_blocks("tool_result") if block.get("id", "")
|
||||
]
|
||||
|
||||
# Calculate extra tokens needed for dependent tool_use messages
|
||||
extra_tokens = 0
|
||||
dependent_indices: set[int] = set()
|
||||
|
||||
for tool_id in tool_result_ids:
|
||||
if tool_id in tool_use_locations:
|
||||
tool_use_idx = tool_use_locations[tool_id]
|
||||
if tool_use_idx not in keep_indices and tool_use_idx != i:
|
||||
dependent_indices.add(tool_use_idx)
|
||||
_, dep_stat = msg_stats[tool_use_idx]
|
||||
extra_tokens += dep_stat.total_tokens
|
||||
|
||||
# Check if we can fit this message plus its dependencies within reserve
|
||||
if accumulated_tokens + stat.total_tokens + extra_tokens > memory_compact_reserve:
|
||||
logger.info(
|
||||
"Context check: message %d requires %d extra tokens for tool_use dependencies, "
|
||||
"total would exceed reserve %d",
|
||||
i,
|
||||
extra_tokens,
|
||||
memory_compact_reserve,
|
||||
)
|
||||
break
|
||||
|
||||
# Add this message and its dependencies
|
||||
keep_indices.add(i)
|
||||
keep_indices.update(dependent_indices)
|
||||
accumulated_tokens += stat.total_tokens + extra_tokens
|
||||
|
||||
# Build final lists based on keep_indices (preserve original order)
|
||||
messages_to_compact = []
|
||||
messages_to_keep = []
|
||||
|
||||
for idx, (msg, _) in enumerate(msg_stats):
|
||||
if idx in keep_indices:
|
||||
messages_to_keep.append(msg)
|
||||
else:
|
||||
messages_to_compact.append(msg)
|
||||
|
||||
# Validate tool ids alignment for messages_to_keep
|
||||
tools_aligned = self.validate_tool_ids_alignment(messages_to_keep)
|
||||
|
||||
logger.info(
|
||||
"Context check result: %d messages to compact, %d messages to keep, "
|
||||
"total tokens: %d, threshold: %d, reserve: %d, kept tokens: %d, "
|
||||
"tools_aligned: %s",
|
||||
len(messages_to_compact),
|
||||
len(messages_to_keep),
|
||||
total_tokens,
|
||||
memory_compact_threshold,
|
||||
memory_compact_reserve,
|
||||
accumulated_tokens,
|
||||
tools_aligned,
|
||||
)
|
||||
|
||||
return messages_to_compact, messages_to_keep, tools_aligned
|
||||
112
reme/memory/file_based/utils/file_utils.py
Normal file
112
reme/memory/file_based/utils/file_utils.py
Normal file
|
|
@ -0,0 +1,112 @@
|
|||
"""Shared utilities for file and shell tools."""
|
||||
|
||||
# Default truncation limits
|
||||
DEFAULT_MAX_LINES = 1000
|
||||
DEFAULT_MAX_BYTES = 30 * 1024 # 30KB
|
||||
|
||||
|
||||
def truncate_output(
|
||||
text: str,
|
||||
max_lines: int = DEFAULT_MAX_LINES,
|
||||
max_bytes: int = DEFAULT_MAX_BYTES,
|
||||
keep: str = "head",
|
||||
) -> tuple[str, bool, int, str]:
|
||||
"""Smart truncation for large content.
|
||||
|
||||
Args:
|
||||
text: Text content to truncate.
|
||||
max_lines: Maximum number of lines.
|
||||
max_bytes: Maximum size in bytes.
|
||||
keep: Which part to keep - "head" (first lines) or "tail" (last lines).
|
||||
|
||||
Returns:
|
||||
(truncated_content, was_truncated, output_line_count, truncate_reason)
|
||||
"""
|
||||
if not text:
|
||||
return text, False, 0, ""
|
||||
|
||||
lines = text.split("\n")
|
||||
total_lines = len(lines)
|
||||
|
||||
# No truncation needed
|
||||
if total_lines <= max_lines and len(text.encode("utf-8")) <= max_bytes:
|
||||
return text, False, total_lines, ""
|
||||
|
||||
# Apply line limit
|
||||
if total_lines > max_lines:
|
||||
if keep == "tail":
|
||||
lines = lines[-max_lines:]
|
||||
else:
|
||||
lines = lines[:max_lines]
|
||||
reason = "lines"
|
||||
else:
|
||||
reason = ""
|
||||
|
||||
# Apply byte limit
|
||||
if len("\n".join(lines).encode("utf-8")) > max_bytes:
|
||||
if keep == "tail":
|
||||
while lines and len("\n".join(lines).encode("utf-8")) > max_bytes:
|
||||
lines.pop(0)
|
||||
else:
|
||||
truncated = []
|
||||
current_bytes = 0
|
||||
for line in lines:
|
||||
line_bytes = len(line.encode("utf-8")) + 1
|
||||
if current_bytes + line_bytes > max_bytes:
|
||||
break
|
||||
truncated.append(line)
|
||||
current_bytes += line_bytes
|
||||
lines = truncated
|
||||
reason = "bytes"
|
||||
|
||||
return "\n".join(lines), True, len(lines), reason
|
||||
|
||||
|
||||
def truncate_shell_output(text: str) -> str:
|
||||
"""Truncate shell output to last N lines or M bytes, with truncation notice.
|
||||
|
||||
Args:
|
||||
text: The output text to truncate.
|
||||
|
||||
Returns:
|
||||
Truncated text with notice if truncated.
|
||||
"""
|
||||
if not text:
|
||||
return text
|
||||
|
||||
try:
|
||||
total_lines = len(text.split("\n"))
|
||||
truncated, was_truncated, output_lines, reason = truncate_output(text, keep="tail")
|
||||
|
||||
if not was_truncated:
|
||||
return text
|
||||
|
||||
start_line = total_lines - output_lines + 1
|
||||
if reason == "lines":
|
||||
notice = f"\n\n[Output truncated: showing lines {start_line}-{total_lines} of {total_lines} total]"
|
||||
else:
|
||||
notice = (
|
||||
f"\n\n[Output truncated: showing lines {start_line}-{total_lines} of {total_lines} "
|
||||
f"({DEFAULT_MAX_BYTES // 1024}KB limit)]"
|
||||
)
|
||||
|
||||
return truncated + notice
|
||||
except Exception:
|
||||
return text
|
||||
|
||||
|
||||
def read_file_safe(file_path: str) -> str:
|
||||
"""Read file with Unicode error handling.
|
||||
|
||||
Args:
|
||||
file_path: Path to the file.
|
||||
|
||||
Returns:
|
||||
File content as string.
|
||||
"""
|
||||
try:
|
||||
with open(file_path, "r", encoding="utf-8") as f:
|
||||
return f.read()
|
||||
except UnicodeDecodeError:
|
||||
with open(file_path, "r", encoding="utf-8", errors="ignore") as f:
|
||||
return f.read()
|
||||
|
|
@ -3,8 +3,6 @@
|
|||
from .base_memory_tool import BaseMemoryTool
|
||||
|
||||
# chunk tools
|
||||
from .chunk.memory_get import MemoryGet
|
||||
from .chunk.memory_search import MemorySearch
|
||||
from .delegate_task import DelegateTask
|
||||
|
||||
# history tools
|
||||
|
|
@ -36,9 +34,6 @@ __all__ = [
|
|||
# base
|
||||
"BaseMemoryTool",
|
||||
"DelegateTask",
|
||||
# chunk tools
|
||||
"MemoryGet",
|
||||
"MemorySearch",
|
||||
# history tools
|
||||
"AddHistory",
|
||||
"ReadHistory",
|
||||
|
|
@ -7,7 +7,7 @@ from .config import ReMeConfigParser
|
|||
from .core import Application
|
||||
from .core.enumeration import MemoryType, Role
|
||||
from .core.schema import Message, MemoryNode
|
||||
from .memory.tools import (
|
||||
from .memory.vector_tools import (
|
||||
AddDraftAndRetrieveSimilarMemory,
|
||||
AddHistory,
|
||||
AddMemory,
|
||||
|
|
@ -17,8 +17,8 @@ from .memory.tools import (
|
|||
RetrieveMemory,
|
||||
UpdateProfilesV1,
|
||||
)
|
||||
from .memory.tools.profiles.profile_handler import ProfileHandler
|
||||
from .memory.tools.record.memory_handler import MemoryHandler
|
||||
from .memory.vector_tools.profiles.profile_handler import ProfileHandler
|
||||
from .memory.vector_tools.record.memory_handler import MemoryHandler
|
||||
from .memory.vector_based import (
|
||||
BaseMemoryAgent,
|
||||
PersonalRetriever,
|
||||
|
|
@ -185,7 +185,7 @@ class ReMe(Application):
|
|||
format_messages.append(message)
|
||||
|
||||
if version == "default":
|
||||
personal_summarizer_tools = [
|
||||
personal_summarizer_tools: list = [
|
||||
AddDraftAndRetrieveSimilarMemory(
|
||||
enable_thinking_params=enable_thinking_params,
|
||||
enable_memory_target=False,
|
||||
|
|
|
|||
183
reme/reme_fb.py
183
reme/reme_fb.py
|
|
@ -1,183 +0,0 @@
|
|||
"""ReMe File Based"""
|
||||
|
||||
from pathlib import Path
|
||||
|
||||
from .config import ReMeConfigParser
|
||||
from .core import Application
|
||||
from .core.schema import Message
|
||||
from .core.tools import (
|
||||
BashTool,
|
||||
EditTool,
|
||||
LsTool,
|
||||
ReadTool,
|
||||
WriteTool,
|
||||
)
|
||||
from .memory.file_based import FbCompactor, FbContextChecker, FbSummarizer
|
||||
from .memory.tools import MemoryGet, MemorySearch
|
||||
|
||||
|
||||
class ReMeFb(Application):
|
||||
"""ReMe File Based"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
*args,
|
||||
working_dir: str = ".reme",
|
||||
config_path: str = "file",
|
||||
enable_logo: bool = True,
|
||||
log_to_console: bool = True,
|
||||
llm_api_key: str | None = None,
|
||||
llm_base_url: str | None = None,
|
||||
embedding_api_key: str | None = None,
|
||||
embedding_base_url: str | None = None,
|
||||
default_llm_config: dict | None = None,
|
||||
default_embedding_model_config: dict | None = None,
|
||||
default_file_store_config: dict | None = None,
|
||||
default_token_counter_config: dict | None = None,
|
||||
default_file_watcher_config: dict | None = None,
|
||||
context_window_tokens: int = 128000,
|
||||
reserve_tokens: int = 36000,
|
||||
keep_recent_tokens: int = 20000,
|
||||
vector_weight: float = 0.7,
|
||||
candidate_multiplier: float = 3.0,
|
||||
**kwargs,
|
||||
):
|
||||
"""Initialize ReMe with config."""
|
||||
working_path = Path(working_dir)
|
||||
working_path.mkdir(parents=True, exist_ok=True)
|
||||
memory_path = working_path / "memory"
|
||||
memory_path.mkdir(parents=True, exist_ok=True)
|
||||
self.working_dir: str = str(working_path.absolute())
|
||||
|
||||
default_file_watcher_config = default_file_watcher_config or {}
|
||||
if not default_file_watcher_config.get("watch_paths", None):
|
||||
default_file_watcher_config["watch_paths"] = [
|
||||
str(working_path / "MEMORY.md"),
|
||||
str(working_path / "memory.md"),
|
||||
str(memory_path),
|
||||
]
|
||||
super().__init__(
|
||||
*args,
|
||||
llm_api_key=llm_api_key,
|
||||
llm_base_url=llm_base_url,
|
||||
embedding_api_key=embedding_api_key,
|
||||
embedding_base_url=embedding_base_url,
|
||||
working_dir=working_dir,
|
||||
config_path=config_path,
|
||||
enable_logo=enable_logo,
|
||||
log_to_console=log_to_console,
|
||||
parser=ReMeConfigParser,
|
||||
default_llm_config=default_llm_config,
|
||||
default_embedding_model_config=default_embedding_model_config,
|
||||
default_file_store_config=default_file_store_config,
|
||||
default_token_counter_config=default_token_counter_config,
|
||||
default_file_watcher_config=default_file_watcher_config,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
self.service_config.metadata.setdefault("context_window_tokens", context_window_tokens)
|
||||
self.service_config.metadata.setdefault("reserve_tokens", reserve_tokens)
|
||||
self.service_config.metadata.setdefault("keep_recent_tokens", keep_recent_tokens)
|
||||
self.service_config.metadata.setdefault("vector_weight", vector_weight)
|
||||
self.service_config.metadata.setdefault("candidate_multiplier", candidate_multiplier)
|
||||
|
||||
async def context_check(self, messages: list[Message | dict]) -> dict:
|
||||
"""Check if messages exceed context limits."""
|
||||
checker = FbContextChecker(
|
||||
context_window_tokens=self.service_config.metadata["context_window_tokens"],
|
||||
reserve_tokens=self.service_config.metadata["reserve_tokens"],
|
||||
keep_recent_tokens=self.service_config.metadata["keep_recent_tokens"],
|
||||
)
|
||||
return await checker.call(messages=messages, service_context=self.service_context)
|
||||
|
||||
async def compact(
|
||||
self,
|
||||
messages_to_summarize: list[Message | dict] = None,
|
||||
turn_prefix_messages: list[Message | dict] = None,
|
||||
previous_summary: str = "",
|
||||
language: str = "zh",
|
||||
**kwargs,
|
||||
) -> str | dict:
|
||||
"""Compact messages into a summary."""
|
||||
compactor = FbCompactor(language=language, **kwargs)
|
||||
return await compactor.call(
|
||||
messages_to_summarize=messages_to_summarize or [],
|
||||
turn_prefix_messages=turn_prefix_messages or [],
|
||||
previous_summary=previous_summary,
|
||||
service_context=self.service_context,
|
||||
)
|
||||
|
||||
async def summary(
|
||||
self,
|
||||
messages: list[Message | dict],
|
||||
date: str,
|
||||
version: str = "default",
|
||||
language: str = "zh",
|
||||
**kwargs,
|
||||
) -> str | dict:
|
||||
"""Generate a summary of the given messages."""
|
||||
summarizer = FbSummarizer(
|
||||
tools=[
|
||||
BashTool(cwd=self.working_dir),
|
||||
LsTool(cwd=self.working_dir),
|
||||
ReadTool(cwd=self.working_dir),
|
||||
WriteTool(cwd=self.working_dir),
|
||||
EditTool(cwd=self.working_dir),
|
||||
],
|
||||
working_dir=self.working_dir,
|
||||
language=language,
|
||||
version=version,
|
||||
**kwargs,
|
||||
)
|
||||
return await summarizer.call(messages=messages, date=date, service_context=self.service_context)
|
||||
|
||||
async def memory_search(self, query: str, max_results: int = 5, min_score: float = 0.1) -> str:
|
||||
"""
|
||||
Mandatory recall step: semantically search MEMORY.md + memory/*.md (and optional session transcripts)
|
||||
before answering questions about prior work, decisions, dates, people, preferences, or todos;
|
||||
returns top snippets with path + lines.
|
||||
|
||||
Args:
|
||||
query: The semantic search query to find relevant memory snippets
|
||||
max_results: Maximum number of search results to return (optional), default is 5
|
||||
min_score: Minimum similarity score threshold for results (optional), default is 0.1
|
||||
|
||||
Returns:
|
||||
Search results as formatted string
|
||||
"""
|
||||
search_tool = MemorySearch(
|
||||
vector_weight=self.service_config.metadata["vector_weight"],
|
||||
candidate_multiplier=self.service_config.metadata["candidate_multiplier"],
|
||||
)
|
||||
return await search_tool.call(
|
||||
query=query,
|
||||
max_results=max_results,
|
||||
min_score=min_score,
|
||||
service_context=self.service_context,
|
||||
)
|
||||
|
||||
async def memory_get(self, path: str, offset: int | None = None, limit: int | None = None) -> str:
|
||||
"""
|
||||
Safe snippet read from MEMORY.md, memory/*.md with optional offset/limit;
|
||||
use after memory_search to pull only the needed lines and keep context small.
|
||||
|
||||
Args:
|
||||
path: Path to the memory file to read (relative or absolute)
|
||||
offset: Starting line number (1-indexed, optional)
|
||||
limit: Number of lines to read from the starting line (optional)
|
||||
|
||||
Returns:
|
||||
Memory file content as string
|
||||
"""
|
||||
get_tool = MemoryGet(cwd=self.working_dir)
|
||||
return await get_tool.call(path=path, offset=offset, limit=limit, service_context=self.service_context)
|
||||
|
||||
async def needs_compaction(self, messages: list[Message | dict]) -> bool:
|
||||
"""Check if messages need compaction based on context window limits."""
|
||||
messages = [Message(**message) if isinstance(message, dict) else message for message in messages]
|
||||
checker = FbContextChecker(
|
||||
context_window_tokens=self.service_config.metadata["context_window_tokens"],
|
||||
reserve_tokens=self.service_config.metadata["reserve_tokens"],
|
||||
)
|
||||
result = await checker.call(messages=messages, service_context=self.service_context)
|
||||
return result["needs_compaction"]
|
||||
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue