mirror of
https://github.com/abhigyanpatwari/GitNexus.git
synced 2026-09-29 01:41:42 +00:00
Merge branch 'main' into fix-v-001-mcp-bridge-path-traversal
This commit is contained in:
 Gergő Magyar
GitHub
commit
a328db0ccd
110 changed files with 10352 additions and 1443 deletions
|
|
@ -17,11 +17,11 @@ npx gitnexus analyze
|
|||
|
||||
Run from the project root. This parses all source files, builds the knowledge graph, writes it to `.gitnexus/`, and generates CLAUDE.md / AGENTS.md context files.
|
||||
|
||||
| Flag | Effect |
|
||||
| ------------------- | ------------------------------------------------------------------------------------------------------- |
|
||||
| `--force` | Force full re-index even if up to date |
|
||||
| `--embeddings` | Enable embedding generation for semantic search (off by default) |
|
||||
| `--drop-embeddings` | Drop existing embeddings on rebuild. By default, an `analyze` without `--embeddings` preserves them. |
|
||||
| Flag | Effect |
|
||||
| -------------- | ---------------------------------------------------------------- |
|
||||
| `--force` | Force full re-index even if up to date |
|
||||
| `--embeddings` | Enable embedding generation for semantic search (off by default) |
|
||||
| `--drop-embeddings` | Drop existing embeddings on rebuild. By default, an `analyze` without `--embeddings` preserves them. |
|
||||
|
||||
**When to run:** First time in a project, after major code changes, or when `gitnexus://repo/{name}/context` reports the index is stale. In Claude Code, a PostToolUse hook detects staleness after `git commit` and `git merge` and notifies the agent to run `analyze` — the hook does not run analyze itself, to avoid blocking the agent for up to 120s and risking KuzuDB corruption on timeout.
|
||||
|
||||
|
|
|
|||
149
AGENTS.md
149
AGENTS.md
|
|
@ -62,131 +62,64 @@ Commands and gotchas live under **Repo reference** below and in **[CONTRIBUTING.
|
|||
<!-- gitnexus:start -->
|
||||
# GitNexus — Code Intelligence
|
||||
|
||||
Indexed as **GitNexus** (4325 symbols, 10556 relationships, 300 execution flows). Use MCP tools to understand code, assess impact, and navigate safely.
|
||||
This project is indexed by GitNexus as **GitNexus** (26675 symbols, 35395 relationships, 300 execution flows). Use the GitNexus MCP tools to understand code, assess impact, and navigate safely.
|
||||
|
||||
> If any tool warns the index is stale, run `npx gitnexus analyze` first.
|
||||
> If any GitNexus tool warns the index is stale, run `npx gitnexus analyze` in terminal first.
|
||||
|
||||
## Always Do
|
||||
|
||||
- **MUST run impact analysis before editing any symbol.** `gitnexus_impact({target: "symbolName", direction: "upstream"})` — report blast radius to the user.
|
||||
- **MUST run `gitnexus_detect_changes()` before committing** — verify only expected symbols and flows are affected.
|
||||
- **MUST warn the user** if impact returns HIGH or CRITICAL risk.
|
||||
- Explore unfamiliar code with `gitnexus_query({query: "concept"})` (process-grouped, ranked) instead of grepping.
|
||||
- Full context on a symbol: `gitnexus_context({name: "symbolName"})`.
|
||||
|
||||
## When Debugging
|
||||
|
||||
1. `gitnexus_query({query: "<error or symptom>"})` — find related execution flows
|
||||
2. `gitnexus_context({name: "<suspect function>"})` — callers, callees, process participation
|
||||
3. `READ gitnexus://repo/GitNexus/process/{processName}` — trace flow step by step
|
||||
4. Regressions: `gitnexus_detect_changes({scope: "compare", base_ref: "main"})`
|
||||
|
||||
## When Refactoring
|
||||
|
||||
- **Rename:** `gitnexus_rename({symbol_name: "old", new_name: "new", dry_run: true})` first. Graph edits are safe; text_search edits need manual review.
|
||||
- **Extract/Split:** `gitnexus_context` (incoming/outgoing refs) then `gitnexus_impact` (upstream callers) before moving code.
|
||||
- **After any refactor:** `gitnexus_detect_changes({scope: "all"})` to verify scope.
|
||||
- **MUST run impact analysis before editing any symbol.** Before modifying a function, class, or method, run `gitnexus_impact({target: "symbolName", direction: "upstream"})` and report the blast radius (direct callers, affected processes, risk level) to the user.
|
||||
- **MUST run `gitnexus_detect_changes()` before committing** to verify your changes only affect expected symbols and execution flows.
|
||||
- **MUST warn the user** if impact analysis returns HIGH or CRITICAL risk before proceeding with edits.
|
||||
- When exploring unfamiliar code, use `gitnexus_query({query: "concept"})` to find execution flows instead of grepping. It returns process-grouped results ranked by relevance.
|
||||
- When you need full context on a specific symbol — callers, callees, which execution flows it participates in — use `gitnexus_context({name: "symbolName"})`.
|
||||
|
||||
## Never Do
|
||||
|
||||
- Edit a symbol without running `gitnexus_impact` first.
|
||||
- Ignore HIGH/CRITICAL risk warnings.
|
||||
- Rename with find-and-replace — use `gitnexus_rename`.
|
||||
- Commit without `gitnexus_detect_changes()`.
|
||||
- Add language-specific behavior to shared ingestion code (`gitnexus/src/core/ingestion/`) — use a `LanguageProvider` hook. Seeing `provider.mroStrategy === 'xxx'` or an import from `languages/xxx.ts` in shared code means stop and add a hook.
|
||||
|
||||
## Tools Quick Reference
|
||||
|
||||
| Tool | When to use | Example |
|
||||
|------|-------------|---------|
|
||||
| `list_repos` | Discover indexed repos | `gitnexus_list_repos({})` |
|
||||
| `query` | Find code by concept | `gitnexus_query({query: "auth validation"})` |
|
||||
| `context` | 360-degree view of one symbol | `gitnexus_context({name: "validateUser"})` |
|
||||
| `impact` | Blast radius before editing | `gitnexus_impact({target: "X", direction: "upstream"})` |
|
||||
| `detect_changes` | Pre-commit scope check | `gitnexus_detect_changes({scope: "staged"})` |
|
||||
| `rename` | Safe multi-file rename | `gitnexus_rename({symbol_name: "old", new_name: "new", dry_run: true})` |
|
||||
| `cypher` | Custom graph queries | `gitnexus_cypher({query: "MATCH ..."})` |
|
||||
| `api_impact` | Pre-change API route impact | `gitnexus_api_impact({route: "/api/users", method: "GET"})` |
|
||||
| `route_map` | Route → handler → consumer map | `gitnexus_route_map({})` |
|
||||
| `tool_map` | MCP/RPC tool definitions | `gitnexus_tool_map({})` |
|
||||
| `shape_check` | Response shape vs consumer access | `gitnexus_shape_check({route: "/api/users"})` |
|
||||
| `group_list` | List repo groups | `gitnexus_group_list({})` |
|
||||
| `group_sync` | Rebuild group Contract Registry | `gitnexus_group_sync({name: "myGroup"})` |
|
||||
| `query` (group mode) | Cross-repo search in a group (RRF-merged) | `gitnexus_query({repo: "@myGroup", query: "auth"})` |
|
||||
| `context` (group mode) | 360° view across all member repos | `gitnexus_context({repo: "@myGroup", name: "validateUser"})` |
|
||||
| `impact` (group mode) | Cross-repo blast radius via Contract Bridge | `gitnexus_impact({repo: "@myGroup", target: "X", direction: "upstream"})` |
|
||||
|
||||
> Group mode: pass `repo: "@<groupName>"` to fan out across all member repos, or `repo: "@<groupName>/<memberPath>"` to target a single member (path keys from `group.yaml`). Optional `service: "<monorepo/path>"` filters by service root. Group-level state (contracts, staleness) lives in the resources table below — there are **no** `group_query` / `group_context` / `group_impact` / `group_contracts` / `group_status` MCP tools.
|
||||
>
|
||||
> For a full walkthrough of setting up a group across multiple repos that communicate over gRPC, see [docs/guides/microservices-grpc.md](docs/guides/microservices-grpc.md).
|
||||
|
||||
## Impact Risk Levels
|
||||
|
||||
| Depth | Meaning | Action |
|
||||
|-------|---------|--------|
|
||||
| d=1 | WILL BREAK — direct callers/importers | MUST update |
|
||||
| d=2 | LIKELY AFFECTED — indirect deps | Should test |
|
||||
| d=3 | MAY NEED TESTING — transitive | Test if critical path |
|
||||
- NEVER edit a function, class, or method without first running `gitnexus_impact` on it.
|
||||
- NEVER ignore HIGH or CRITICAL risk warnings from impact analysis.
|
||||
- NEVER rename symbols with find-and-replace — use `gitnexus_rename` which understands the call graph.
|
||||
- NEVER commit changes without running `gitnexus_detect_changes()` to check affected scope.
|
||||
|
||||
## Resources
|
||||
|
||||
| Resource | Use for |
|
||||
|----------|---------|
|
||||
| `gitnexus://repo/GitNexus/context` | Codebase overview, index freshness |
|
||||
| `gitnexus://repo/GitNexus/context` | Codebase overview, check index freshness |
|
||||
| `gitnexus://repo/GitNexus/clusters` | All functional areas |
|
||||
| `gitnexus://repo/GitNexus/processes` | All execution flows |
|
||||
| `gitnexus://repo/GitNexus/process/{name}` | Step-by-step execution trace |
|
||||
| `gitnexus://group/{name}/contracts` | Group Contract Registry (provider/consumer rows + cross-links) |
|
||||
| `gitnexus://group/{name}/status` | Per-member index + Contract Registry staleness report |
|
||||
|
||||
## Self-Check Before Finishing
|
||||
## CLI
|
||||
|
||||
1. `gitnexus_impact` was run for all modified symbols
|
||||
2. No HIGH/CRITICAL warnings were ignored
|
||||
3. `gitnexus_detect_changes()` confirms expected scope
|
||||
4. All d=1 dependents were updated
|
||||
|
||||
## Keeping the Index Fresh
|
||||
|
||||
```bash
|
||||
npx gitnexus analyze # incremental by default; preserves embeddings
|
||||
npx gitnexus analyze --force # full rebuild from scratch (opt out of incremental)
|
||||
npx gitnexus analyze --embeddings # also generate embeddings for new/changed nodes
|
||||
npx gitnexus analyze --drop-embeddings # explicit opt-in to wipe existing embeddings
|
||||
```
|
||||
|
||||
`analyze` runs **incrementally by default**. The pipeline still parses every file every run (cross-file resolution requires it), but tree-sitter parsing is **served from a content-addressed cache** under `.gitnexus/parse-cache/` (per-chunk JSON shards plus `index.json`) for chunks whose file contents haven't changed since the last run. Older installs may still have a legacy single file `.gitnexus/parse-cache.json`, which is read for backward compatibility but no longer written. Only changed-file rows (and their importers) are rewritten in LadybugDB; unchanged-file rows are preserved. Output is byte-equivalent to a full rebuild. Pass `--force` to wipe and re-index from scratch (e.g., to recover from a corrupt index, or after upgrading GitNexus).
|
||||
|
||||
The parse cache key is **content-addressed and version-tagged**: it survives `--force` runs, and is automatically invalidated by a `gitnexus` package upgrade (so a new tree-sitter grammar doesn't silently replay stale parse output). Safe to delete the whole `.gitnexus/parse-cache/` directory (and remove any legacy `.gitnexus/parse-cache.json` if present) at any time — it'll be rebuilt on the next analyze.
|
||||
|
||||
Check `.gitnexus/meta.json` `stats.embeddings` (0 = none). A plain `analyze` no longer drops existing vectors — pass `--drop-embeddings` to wipe.
|
||||
|
||||
> Claude Code: PostToolUse hook detects a stale index after `git commit` and `git merge` and prompts the agent to run `analyze`. The hook does not invoke `analyze` itself.
|
||||
|
||||
## CLI Skills
|
||||
|
||||
| Task | Skill file |
|
||||
|------|-----------|
|
||||
| Architecture / "How does X work?" | `.claude/skills/gitnexus/gitnexus-exploring/SKILL.md` |
|
||||
| Blast radius / "What breaks?" | `.claude/skills/gitnexus/gitnexus-impact-analysis/SKILL.md` |
|
||||
| Debugging / "Why is X failing?" | `.claude/skills/gitnexus/gitnexus-debugging/SKILL.md` |
|
||||
| Refactoring | `.claude/skills/gitnexus/gitnexus-refactoring/SKILL.md` |
|
||||
| Tools/resources/schema reference | `.claude/skills/gitnexus/gitnexus-guide/SKILL.md` |
|
||||
| CLI commands (index, status, clean, wiki) | `.claude/skills/gitnexus/gitnexus-cli/SKILL.md` |
|
||||
|
||||
## Hook env knobs
|
||||
|
||||
The Claude Code hook (`gitnexus/hooks/claude/gitnexus-hook.cjs` and the mirrored plugin copy under `gitnexus-claude-plugin/hooks/`) honours these env vars. Defaults work for normal installations; set them only to override resolution. All path overrides ignore values that do not exist on disk and fall through to the standard resolution chain.
|
||||
|
||||
| Env var | Type | Default | Purpose |
|
||||
|---------|------|---------|---------|
|
||||
| `GITNEXUS_HOOK_CLI_PATH` | path | resolved via package layout / `require.resolve` | Override path to the `gitnexus` CLI entry the hook spawns for `augment`. |
|
||||
| `GITNEXUS_HOOK_LSOF_PATH` | path | `lsof` on `PATH` (with `/usr/bin/lsof`, `/usr/sbin/lsof`, `/sbin/lsof` fallbacks) | Override POSIX `lsof` location for the DB-lock probe. |
|
||||
| `GITNEXUS_HOOK_PS_PATH` | path | `ps` on `PATH` (with `/bin/ps`, `/usr/bin/ps` fallbacks) | Override POSIX `ps` location. |
|
||||
| `GITNEXUS_HOOK_POWERSHELL_PATH` | path | `%SystemRoot%\System32\WindowsPowerShell\v1.0\powershell.exe` (then `SysWOW64`, then `powershell.exe` on `PATH`) | Override Windows PowerShell location used by the Restart-Manager probe. |
|
||||
| `GITNEXUS_HOOK_LINUX_PROC_BUDGET_MS` | integer ms | `1200` | Max wall-clock for the Linux `/proc` fd scan before bailing out to the `lsof` fallback. |
|
||||
| `GITNEXUS_HOOK_RM_TARGET` | path | derived | Restart-Manager target file (the LadybugDB path under `.gitnexus/`). Set internally by the hook; rarely overridden manually. |
|
||||
| `GITNEXUS_DEBUG` | boolean (`1`/`true`) | unset | Verbose stderr from the hook: prints discarded augment-stderr prefixes and one-shot `.ps1` load-failure warnings. |
|
||||
| Task | Read this skill file |
|
||||
|------|---------------------|
|
||||
| Understand architecture / "How does X work?" | `.claude/skills/gitnexus/gitnexus-exploring/SKILL.md` |
|
||||
| Blast radius / "What breaks if I change X?" | `.claude/skills/gitnexus/gitnexus-impact-analysis/SKILL.md` |
|
||||
| Trace bugs / "Why is X failing?" | `.claude/skills/gitnexus/gitnexus-debugging/SKILL.md` |
|
||||
| Rename / extract / split / refactor | `.claude/skills/gitnexus/gitnexus-refactoring/SKILL.md` |
|
||||
| Tools, resources, schema reference | `.claude/skills/gitnexus/gitnexus-guide/SKILL.md` |
|
||||
| Index, status, clean, wiki CLI commands | `.claude/skills/gitnexus/gitnexus-cli/SKILL.md` |
|
||||
| Work in the Ingestion area (239 symbols) | `.claude/skills/generated/ingestion/SKILL.md` |
|
||||
| Work in the Extractors area (135 symbols) | `.claude/skills/generated/extractors/SKILL.md` |
|
||||
| Work in the Components area (112 symbols) | `.claude/skills/generated/components/SKILL.md` |
|
||||
| Work in the Lbug area (96 symbols) | `.claude/skills/generated/lbug/SKILL.md` |
|
||||
| Work in the Group area (94 symbols) | `.claude/skills/generated/group/SKILL.md` |
|
||||
| Work in the Cli area (92 symbols) | `.claude/skills/generated/cli/SKILL.md` |
|
||||
| Work in the Configs area (92 symbols) | `.claude/skills/generated/configs/SKILL.md` |
|
||||
| Work in the Type-extractors area (90 symbols) | `.claude/skills/generated/type-extractors/SKILL.md` |
|
||||
| Work in the Hooks area (88 symbols) | `.claude/skills/generated/hooks/SKILL.md` |
|
||||
| Work in the Unit area (80 symbols) | `.claude/skills/generated/unit/SKILL.md` |
|
||||
| Work in the Cpp area (73 symbols) | `.claude/skills/generated/cpp/SKILL.md` |
|
||||
| Work in the Scope-resolution area (72 symbols) | `.claude/skills/generated/scope-resolution/SKILL.md` |
|
||||
| Work in the Server area (66 symbols) | `.claude/skills/generated/server/SKILL.md` |
|
||||
| Work in the Local area (61 symbols) | `.claude/skills/generated/local/SKILL.md` |
|
||||
| Work in the Wiki area (60 symbols) | `.claude/skills/generated/wiki/SKILL.md` |
|
||||
| Work in the Workers area (57 symbols) | `.claude/skills/generated/workers/SKILL.md` |
|
||||
| Work in the Embeddings area (56 symbols) | `.claude/skills/generated/embeddings/SKILL.md` |
|
||||
| Work in the Typescript area (53 symbols) | `.claude/skills/generated/typescript/SKILL.md` |
|
||||
| Work in the Storage area (51 symbols) | `.claude/skills/generated/storage/SKILL.md` |
|
||||
| Work in the Php area (48 symbols) | `.claude/skills/generated/php/SKILL.md` |
|
||||
|
||||
<!-- gitnexus:end -->
|
||||
|
||||
|
|
|
|||
64
CLAUDE.md
64
CLAUDE.md
|
|
@ -52,3 +52,67 @@ If always-on instructions grow, load deep conventions via conditional reads (e.g
|
|||
## GitNexus rules
|
||||
|
||||
See the `<!-- gitnexus:start --> … <!-- gitnexus:end -->` block in **[AGENTS.md](AGENTS.md)** for the canonical MCP tools, impact analysis rules, and index instructions.
|
||||
|
||||
<!-- gitnexus:start -->
|
||||
# GitNexus — Code Intelligence
|
||||
|
||||
This project is indexed by GitNexus as **GitNexus** (26675 symbols, 35395 relationships, 300 execution flows). Use the GitNexus MCP tools to understand code, assess impact, and navigate safely.
|
||||
|
||||
> If any GitNexus tool warns the index is stale, run `npx gitnexus analyze` in terminal first.
|
||||
|
||||
## Always Do
|
||||
|
||||
- **MUST run impact analysis before editing any symbol.** Before modifying a function, class, or method, run `gitnexus_impact({target: "symbolName", direction: "upstream"})` and report the blast radius (direct callers, affected processes, risk level) to the user.
|
||||
- **MUST run `gitnexus_detect_changes()` before committing** to verify your changes only affect expected symbols and execution flows.
|
||||
- **MUST warn the user** if impact analysis returns HIGH or CRITICAL risk before proceeding with edits.
|
||||
- When exploring unfamiliar code, use `gitnexus_query({query: "concept"})` to find execution flows instead of grepping. It returns process-grouped results ranked by relevance.
|
||||
- When you need full context on a specific symbol — callers, callees, which execution flows it participates in — use `gitnexus_context({name: "symbolName"})`.
|
||||
|
||||
## Never Do
|
||||
|
||||
- NEVER edit a function, class, or method without first running `gitnexus_impact` on it.
|
||||
- NEVER ignore HIGH or CRITICAL risk warnings from impact analysis.
|
||||
- NEVER rename symbols with find-and-replace — use `gitnexus_rename` which understands the call graph.
|
||||
- NEVER commit changes without running `gitnexus_detect_changes()` to check affected scope.
|
||||
|
||||
## Resources
|
||||
|
||||
| Resource | Use for |
|
||||
|----------|---------|
|
||||
| `gitnexus://repo/GitNexus/context` | Codebase overview, check index freshness |
|
||||
| `gitnexus://repo/GitNexus/clusters` | All functional areas |
|
||||
| `gitnexus://repo/GitNexus/processes` | All execution flows |
|
||||
| `gitnexus://repo/GitNexus/process/{name}` | Step-by-step execution trace |
|
||||
|
||||
## CLI
|
||||
|
||||
| Task | Read this skill file |
|
||||
|------|---------------------|
|
||||
| Understand architecture / "How does X work?" | `.claude/skills/gitnexus/gitnexus-exploring/SKILL.md` |
|
||||
| Blast radius / "What breaks if I change X?" | `.claude/skills/gitnexus/gitnexus-impact-analysis/SKILL.md` |
|
||||
| Trace bugs / "Why is X failing?" | `.claude/skills/gitnexus/gitnexus-debugging/SKILL.md` |
|
||||
| Rename / extract / split / refactor | `.claude/skills/gitnexus/gitnexus-refactoring/SKILL.md` |
|
||||
| Tools, resources, schema reference | `.claude/skills/gitnexus/gitnexus-guide/SKILL.md` |
|
||||
| Index, status, clean, wiki CLI commands | `.claude/skills/gitnexus/gitnexus-cli/SKILL.md` |
|
||||
| Work in the Ingestion area (239 symbols) | `.claude/skills/generated/ingestion/SKILL.md` |
|
||||
| Work in the Extractors area (135 symbols) | `.claude/skills/generated/extractors/SKILL.md` |
|
||||
| Work in the Components area (112 symbols) | `.claude/skills/generated/components/SKILL.md` |
|
||||
| Work in the Lbug area (96 symbols) | `.claude/skills/generated/lbug/SKILL.md` |
|
||||
| Work in the Group area (94 symbols) | `.claude/skills/generated/group/SKILL.md` |
|
||||
| Work in the Cli area (92 symbols) | `.claude/skills/generated/cli/SKILL.md` |
|
||||
| Work in the Configs area (92 symbols) | `.claude/skills/generated/configs/SKILL.md` |
|
||||
| Work in the Type-extractors area (90 symbols) | `.claude/skills/generated/type-extractors/SKILL.md` |
|
||||
| Work in the Hooks area (88 symbols) | `.claude/skills/generated/hooks/SKILL.md` |
|
||||
| Work in the Unit area (80 symbols) | `.claude/skills/generated/unit/SKILL.md` |
|
||||
| Work in the Cpp area (73 symbols) | `.claude/skills/generated/cpp/SKILL.md` |
|
||||
| Work in the Scope-resolution area (72 symbols) | `.claude/skills/generated/scope-resolution/SKILL.md` |
|
||||
| Work in the Server area (66 symbols) | `.claude/skills/generated/server/SKILL.md` |
|
||||
| Work in the Local area (61 symbols) | `.claude/skills/generated/local/SKILL.md` |
|
||||
| Work in the Wiki area (60 symbols) | `.claude/skills/generated/wiki/SKILL.md` |
|
||||
| Work in the Workers area (57 symbols) | `.claude/skills/generated/workers/SKILL.md` |
|
||||
| Work in the Embeddings area (56 symbols) | `.claude/skills/generated/embeddings/SKILL.md` |
|
||||
| Work in the Typescript area (53 symbols) | `.claude/skills/generated/typescript/SKILL.md` |
|
||||
| Work in the Storage area (51 symbols) | `.claude/skills/generated/storage/SKILL.md` |
|
||||
| Work in the Php area (48 symbols) | `.claude/skills/generated/php/SKILL.md` |
|
||||
|
||||
<!-- gitnexus:end -->
|
||||
|
|
|
|||
174
README.md
174
README.md
|
|
@ -1,4 +1,5 @@
|
|||
# GitNexus
|
||||
|
||||
**⚠️ Important Notice:** GitNexus has NO official cryptocurrency, token, or coin. Any token/coin using the GitNexus name on Pump.fun or any other platform is **not affiliated with, endorsed by, or created by** this project or its maintainers. Do not purchase any cryptocurrency claiming association with GitNexus.
|
||||
|
||||
<div align="center">
|
||||
|
|
@ -30,14 +31,9 @@
|
|||
|
||||
Indexes any codebase into a knowledge graph — every dependency, call chain, cluster, and execution flow — then exposes it through smart tools so AI agents never miss code.
|
||||
|
||||
|
||||
|
||||
|
||||
https://github.com/user-attachments/assets/172685ba-8e54-4ea7-9ad1-e31a3398da72
|
||||
|
||||
|
||||
|
||||
> *Like DeepWiki, but deeper.* DeepWiki helps you *understand* code. GitNexus lets you *analyze* it — because a knowledge graph tracks every relationship, not just descriptions.
|
||||
> _Like DeepWiki, but deeper._ DeepWiki helps you _understand_ code. GitNexus lets you _analyze_ it — because a knowledge graph tracks every relationship, not just descriptions.
|
||||
|
||||
**TL;DR:** The **Web UI** is a quick way to chat with any repo. The **CLI + MCP** is how you make your AI agent actually reliable — it gives Cursor, Claude Code, Codex, and friends a deep architectural view of your codebase so they stop missing dependencies, breaking call chains, and shipping blind edits. Even smaller models get full architectural clarity, making it compete with Goliath models.
|
||||
|
||||
|
|
@ -47,18 +43,17 @@ https://github.com/user-attachments/assets/172685ba-8e54-4ea7-9ad1-e31a3398da72
|
|||
|
||||
[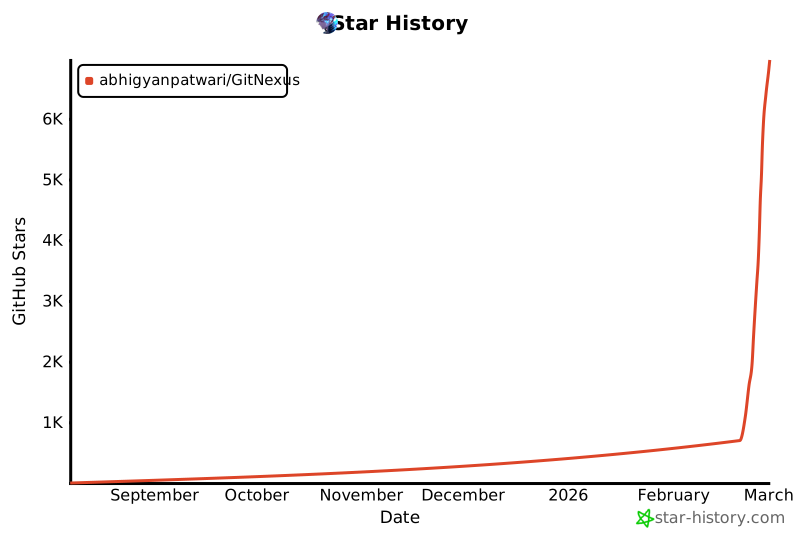](https://www.star-history.com/#abhigyanpatwari/GitNexus&type=date&legend=top-left)
|
||||
|
||||
|
||||
## Two Ways to Use GitNexus
|
||||
|
||||
| | **CLI + MCP** | **Web UI** |
|
||||
| ----------------- | -------------------------------------------------------------- | ------------------------------------------------------------ |
|
||||
| **What** | Index repos locally, connect AI agents via MCP | Visual graph explorer + AI chat in browser |
|
||||
| **For** | Daily development with Cursor, Claude Code, Codex, Windsurf, OpenCode | Quick exploration, demos, one-off analysis |
|
||||
| **Scale** | Full repos, any size | Limited by browser memory (~5k files), or unlimited via backend mode |
|
||||
| **Install** | `npm install -g gitnexus` | No install — [gitnexus.vercel.app](https://gitnexus.vercel.app) |
|
||||
| **Storage** | LadybugDB native (fast, persistent) | LadybugDB WASM (in-memory, per session) |
|
||||
| **Parsing** | Tree-sitter native bindings | Tree-sitter WASM |
|
||||
| **Privacy** | Everything local, no network | Everything in-browser, no server |
|
||||
| | **CLI + MCP** | **Web UI** |
|
||||
| ----------- | --------------------------------------------------------------------- | -------------------------------------------------------------------- |
|
||||
| **What** | Index repos locally, connect AI agents via MCP | Visual graph explorer + AI chat in browser |
|
||||
| **For** | Daily development with Cursor, Claude Code, Codex, Windsurf, OpenCode | Quick exploration, demos, one-off analysis |
|
||||
| **Scale** | Full repos, any size | Limited by browser memory (~5k files), or unlimited via backend mode |
|
||||
| **Install** | `npm install -g gitnexus` | No install — [gitnexus.vercel.app](https://gitnexus.vercel.app) |
|
||||
| **Storage** | LadybugDB native (fast, persistent) | LadybugDB WASM (in-memory, per session) |
|
||||
| **Parsing** | Tree-sitter native bindings | Tree-sitter WASM |
|
||||
| **Privacy** | Everything local, no network | Everything in-browser, no server |
|
||||
|
||||
> **Bridge mode:** `gitnexus serve` connects the two — the web UI auto-detects the local server and can browse all your CLI-indexed repos without re-uploading or re-indexing.
|
||||
|
||||
|
|
@ -69,6 +64,7 @@ https://github.com/user-attachments/assets/172685ba-8e54-4ea7-9ad1-e31a3398da72
|
|||
GitNexus is available as an **enterprise offering** - either as a fully managed **SaaS** or a **self-hosted** deployment. Also available for **commercial use** of the OSS version with proper licensing.
|
||||
|
||||
Enterprise includes:
|
||||
|
||||
- **PR Review** - automated blast radius analysis on pull requests
|
||||
- **Auto-updating Code Wiki** - always up-to-date documentation (Code Wiki is also available in OSS)
|
||||
- **Auto-reindexing** - knowledge graph stays fresh automatically
|
||||
|
|
@ -77,6 +73,7 @@ Enterprise includes:
|
|||
- **Priority feature/language support** - request new languages or features
|
||||
|
||||
**Upcoming:**
|
||||
|
||||
- Auto regression forensics
|
||||
- End-to-end test generation
|
||||
|
||||
|
|
@ -117,13 +114,13 @@ To configure MCP for your editor, run `npx gitnexus setup` once — or set it up
|
|||
|
||||
### Editor Support
|
||||
|
||||
| Editor | MCP | Skills | Hooks (auto-augment) | Support |
|
||||
| --------------------- | --- | ------ | -------------------- | -------------- |
|
||||
| **Claude Code** | Yes | Yes | Yes (PreToolUse + PostToolUse) | **Full** |
|
||||
| **Cursor** | Yes | Yes | Yes (postToolUse, [manual install](gitnexus-cursor-integration/README.md#hook-install)) | **Full** |
|
||||
| **Codex** | Yes | Yes | — | MCP + Skills |
|
||||
| **Windsurf** | Yes | — | — | MCP |
|
||||
| **OpenCode** | Yes | Yes | — | MCP + Skills |
|
||||
| Editor | MCP | Skills | Hooks (auto-augment) | Support |
|
||||
| --------------- | --- | ------ | --------------------------------------------------------------------------------------- | ------------ |
|
||||
| **Claude Code** | Yes | Yes | Yes (PreToolUse + PostToolUse) | **Full** |
|
||||
| **Cursor** | Yes | Yes | Yes (postToolUse, [manual install](gitnexus-cursor-integration/README.md#hook-install)) | **Full** |
|
||||
| **Codex** | Yes | Yes | — | MCP + Skills |
|
||||
| **Windsurf** | Yes | — | — | MCP |
|
||||
| **OpenCode** | Yes | Yes | — | MCP + Skills |
|
||||
|
||||
> **Claude Code** gets the deepest integration: MCP tools + agent skills + PreToolUse hooks that enrich searches with graph context + PostToolUse hooks that detect a stale index after commits and prompt the agent to reindex.
|
||||
|
||||
|
|
@ -131,10 +128,10 @@ To configure MCP for your editor, run `npx gitnexus setup` once — or set it up
|
|||
|
||||
Built by the community — not officially maintained, but worth checking out.
|
||||
|
||||
| Project | Author | Description |
|
||||
|---------|--------|-------------|
|
||||
| [pi-gitnexus](https://github.com/tintinweb/pi-gitnexus) | [@tintinweb](https://github.com/tintinweb) | GitNexus plugin for [pi](https://pi.dev) — `pi install npm:pi-gitnexus` |
|
||||
| [gitnexus-stable-ops](https://github.com/ShunsukeHayashi/gitnexus-stable-ops) | [@ShunsukeHayashi](https://github.com/ShunsukeHayashi) | Stable ops & deployment workflows (Miyabi ecosystem) |
|
||||
| Project | Author | Description |
|
||||
| ----------------------------------------------------------------------------- | ------------------------------------------------------ | ----------------------------------------------------------------------- |
|
||||
| [pi-gitnexus](https://github.com/tintinweb/pi-gitnexus) | [@tintinweb](https://github.com/tintinweb) | GitNexus plugin for [pi](https://pi.dev) — `pi install npm:pi-gitnexus` |
|
||||
| [gitnexus-stable-ops](https://github.com/ShunsukeHayashi/gitnexus-stable-ops) | [@ShunsukeHayashi](https://github.com/ShunsukeHayashi) | Stable ops & deployment workflows (Miyabi ecosystem) |
|
||||
|
||||
> Have a project built on GitNexus? Open a PR to add it here!
|
||||
|
||||
|
|
@ -197,7 +194,8 @@ args = ["-y", "gitnexus@latest", "mcp"]
|
|||
```bash
|
||||
gitnexus setup # Configure MCP for your editors (one-time)
|
||||
gitnexus analyze [path] # Index a repository (or update stale index)
|
||||
gitnexus analyze --force # Force full re-index
|
||||
gitnexus analyze --repair-fts # Fast path: rebuild/verify only FTS indexes on existing index data
|
||||
gitnexus analyze --force # Full rebuild: re-parse + graph rebuild + FTS rebuild
|
||||
gitnexus analyze --skills # Generate repo-specific skill files from detected communities
|
||||
gitnexus analyze --skip-embeddings # Skip embedding generation (faster)
|
||||
gitnexus analyze --skip-agents-md # Preserve custom AGENTS.md/CLAUDE.md gitnexus section edits
|
||||
|
|
@ -205,6 +203,7 @@ gitnexus analyze --skip-git # Index folders that are not Git repositories
|
|||
gitnexus analyze --embeddings # Enable embedding generation (slower, better search)
|
||||
gitnexus analyze --verbose # Log skipped files when parsers are unavailable
|
||||
gitnexus analyze --worker-timeout 60 # Increase worker idle timeout for slow parses
|
||||
gitnexus analyze --workers <n> # Parse worker pool size (default: cores-1, capped at 16; 0 = sequential)
|
||||
gitnexus mcp # Start MCP server (stdio) — serves all indexed repos
|
||||
gitnexus serve # Start local HTTP server (multi-repo) for web UI connection
|
||||
gitnexus list # List all indexed repositories
|
||||
|
|
@ -229,6 +228,25 @@ gitnexus group status <name> # Check staleness of repos in a group
|
|||
|
||||
If `analyze` reports a worker parse timeout on a large or unusual repository, it keeps running and falls back safely. To give slow worker jobs more time, use `gitnexus analyze --worker-timeout 60` or set `GITNEXUS_WORKER_SUB_BATCH_TIMEOUT_MS=60000`. For very large files, `GITNEXUS_WORKER_SUB_BATCH_MAX_BYTES` controls the worker job byte budget.
|
||||
|
||||
#### Environment variables
|
||||
|
||||
Most `analyze` knobs are also CLI flags (`--workers`, `--worker-timeout`, `--max-file-size`, `--verbose`). Use the env-var form when you'd otherwise repeat the same flag every run, or when invoking GitNexus from a long-running host (MCP server, eval-server, CI shell) that already manages its own environment. CLI flags take precedence over env vars; env vars take precedence over built-in defaults.
|
||||
|
||||
| Variable | Default | Effect | Tune when… |
|
||||
| -------------------------------------- | ------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------- |
|
||||
| `GITNEXUS_WORKER_POOL_SIZE` | `cores - 1`, capped at 16 | Parse worker pool size. `0` disables the pool (sequential fallback). Equivalent to `--workers <n>`. | Constrained containers (cgroup CPU limits), CI runners with explicit quotas, or debugging a worker-only crash via `0`. |
|
||||
| `GITNEXUS_PARSE_CHUNK_CONCURRENCY` | `2` | Number of chunks whose file contents may be read into memory in parallel while the pool dispatches the current chunk. Worker dispatch itself stays serial. | Repos large enough to chunk (multi-MB total source) where disk I/O is a measurable fraction of analyze wall-clock. |
|
||||
| `GITNEXUS_VERBOSE` | unset | When `1`, enables verbose ingestion logs (skipped-file warnings, per-chunk throughput, parse-cache stats). Equivalent to `--verbose`. | Debugging an analyze that "completed" but seems to have missed files; tuning `--workers` / chunk concurrency against observable throughput. |
|
||||
| `GITNEXUS_MAX_FILE_SIZE` | `512` (KB) | Walker skip threshold in KB. Hard cap is `32768` (tree-sitter buffer ceiling). Equivalent to `--max-file-size <kb>`. | Indexing repos with intentionally-large source files (generated parsers, vendored bundles) that should still be parsed. |
|
||||
| `GITNEXUS_WORKER_SUB_BATCH_TIMEOUT_MS` | `30000` | Worker idle timeout in milliseconds before retry/fallback. Equivalent to `--worker-timeout <seconds>` × 1000. | Slow-parsing files (large minified JS, deeply-nested TS types) that legitimately need more than 30s. |
|
||||
| `GITNEXUS_WORKER_SUB_BATCH_MAX_BYTES` | `8388608` (8 MB) | Per-job byte budget the pool will send to a worker in one `postMessage`. | Very large individual files; mostly diagnostic — bumping past 8 MB risks structured-clone memory pressure. |
|
||||
| `GITNEXUS_WORKER_MAX_RESPAWNS_PER_SLOT` | `3` | Max replacement spawns per worker slot before the slot is dropped from the active rotation. Bounds respawn loops on a chronically-crashing slot. | Hosts where a flaky worker should retry more (raise) or fail-fast (lower) before the slot is dropped. |
|
||||
| `GITNEXUS_WORKER_MAX_CUMULATIVE_TIMEOUT_MS` | `5 × subBatchTimeoutMs` | Total retry wall-time budget per job before quarantining. Combined with `timeoutBackoffFactor`, prevents exponentially-growing retries from stalling for hours. | Slow files that legitimately need long total retry windows; lower to fail-fast on stalls. |
|
||||
| `GITNEXUS_WORKER_CONSECUTIVE_FAILURE_THRESHOLD`| `max(3, poolSize)` | Per-slot consecutive deaths before the pool's circuit breaker trips. After tripping, every subsequent dispatch rejects until a fresh pool is created. | Hosts where a SIGSEGV-prone native grammar should trip the breaker sooner; CI runners that should fail loudly. |
|
||||
| `GITNEXUS_CHUNK_BYTE_BUDGET` | `2097152` (2 MB) | Chunk boundary used for cache-key composition and dispatch. Smaller = finer-grained cache hits but more dispatch overhead. | Tuning incremental-analyze cache behavior on monorepos. |
|
||||
| `GITNEXUS_NO_GITIGNORE` | unset | When set, skips `.gitignore` parsing. `.gitnexusignore` is still honored. | Indexing a repo whose `.gitignore` excludes files you actually want indexed (e.g., generated code committed for cross-repo lookup). |
|
||||
| `GITNEXUS_SKIP_OPTIONAL_GRAMMARS` | unset | When `=1` strictly, skips native builds for `tree-sitter-dart` / `tree-sitter-proto` at install time. | Installing on a host without a C++ toolchain; you're willing to skip Dart/Proto parsing. |
|
||||
|
||||
#### Publishing to understand-quickly (opt-in)
|
||||
|
||||
[`looptech-ai/understand-quickly`](https://github.com/looptech-ai/understand-quickly) is a public registry of code-knowledge graphs that lists `gitnexus@1` as a first-class format. After registering your repo once (`npx @understand-quickly/cli add` or the [wizard](https://looptech-ai.github.io/understand-quickly/add.html)), `gitnexus publish` fires a single `repository_dispatch` event so the registry resyncs your entry on demand instead of waiting for the nightly job.
|
||||
|
|
@ -239,27 +257,27 @@ It is opt-in and a no-op without `UNDERSTAND_QUICKLY_TOKEN` — a fine-grained G
|
|||
|
||||
**16 tools** exposed via MCP (11 per-repo + 5 group):
|
||||
|
||||
| Tool | What It Does | `repo` Param |
|
||||
| ------------------ | ----------------------------------------------------------------- | -------------- |
|
||||
| `list_repos` | Discover all indexed repositories | — |
|
||||
| `query` | Process-grouped hybrid search (BM25 + semantic + RRF) | Optional |
|
||||
| `context` | 360-degree symbol view — categorized refs, process participation | Optional |
|
||||
| `impact` | Blast radius analysis with depth grouping and confidence | Optional |
|
||||
| `detect_changes` | Git-diff impact — maps changed lines to affected processes | Optional |
|
||||
| `rename` | Multi-file coordinated rename with graph + text search | Optional |
|
||||
| `cypher` | Raw Cypher graph queries | Optional |
|
||||
| `group_list` | List configured repository groups | — |
|
||||
| `group_sync` | Extract contracts and match across repos/services | — |
|
||||
| `group_contracts`| Inspect extracted contracts and cross-links | — |
|
||||
| `group_query` | Search execution flows across all repos in a group | — |
|
||||
| `group_status` | Check staleness of repos in a group | — |
|
||||
| Tool | What It Does | `repo` Param |
|
||||
| ----------------- | ---------------------------------------------------------------- | ------------ |
|
||||
| `list_repos` | Discover all indexed repositories | — |
|
||||
| `query` | Process-grouped hybrid search (BM25 + semantic + RRF) | Optional |
|
||||
| `context` | 360-degree symbol view — categorized refs, process participation | Optional |
|
||||
| `impact` | Blast radius analysis with depth grouping and confidence | Optional |
|
||||
| `detect_changes` | Git-diff impact — maps changed lines to affected processes | Optional |
|
||||
| `rename` | Multi-file coordinated rename with graph + text search | Optional |
|
||||
| `cypher` | Raw Cypher graph queries | Optional |
|
||||
| `group_list` | List configured repository groups | — |
|
||||
| `group_sync` | Extract contracts and match across repos/services | — |
|
||||
| `group_contracts` | Inspect extracted contracts and cross-links | — |
|
||||
| `group_query` | Search execution flows across all repos in a group | — |
|
||||
| `group_status` | Check staleness of repos in a group | — |
|
||||
|
||||
> When only one repo is indexed, the `repo` parameter is optional. With multiple repos, specify which one: `query({query: "auth", repo: "my-app"})`.
|
||||
|
||||
**Resources** for instant context:
|
||||
|
||||
| Resource | Purpose |
|
||||
| ----------------------------------------- | ---------------------------------------------------- |
|
||||
| Resource | Purpose |
|
||||
| --------------------------------------- | ---------------------------------------------------- |
|
||||
| `gitnexus://repos` | List all indexed repositories (read this first) |
|
||||
| `gitnexus://repo/{name}/context` | Codebase stats, staleness check, and available tools |
|
||||
| `gitnexus://repo/{name}/clusters` | All functional clusters with cohesion scores |
|
||||
|
|
@ -270,9 +288,9 @@ It is opt-in and a no-op without `UNDERSTAND_QUICKLY_TOKEN` — a fine-grained G
|
|||
|
||||
**2 MCP prompts** for guided workflows:
|
||||
|
||||
| Prompt | What It Does |
|
||||
| ----------------- | ------------------------------------------------------------------------- |
|
||||
| `detect_impact` | Pre-commit change analysis — scope, affected processes, risk level |
|
||||
| Prompt | What It Does |
|
||||
| --------------- | ------------------------------------------------------------------------- |
|
||||
| `detect_impact` | Pre-commit change analysis — scope, affected processes, risk level |
|
||||
| `generate_map` | Architecture documentation from the knowledge graph with mermaid diagrams |
|
||||
|
||||
**4 agent skills** installed to `.claude/skills/` automatically:
|
||||
|
|
@ -359,10 +377,10 @@ npx gitnexus@latest serve
|
|||
|
||||
The official Docker setup ships **two signed images** orchestrated by `docker-compose.yaml`. Each image is published to both **GitHub Container Registry** (GHCR) and **Docker Hub** — same build, same digest, same Cosign signature — so pick whichever registry you prefer:
|
||||
|
||||
| Purpose | GHCR (default in `docker-compose.yaml`) | Docker Hub mirror |
|
||||
| ---------------------------------------------------------------------- | --------------------------------------------- | ------------------------------------------- |
|
||||
| CLI / `gitnexus serve` backend (HTTP API on port `4747`, MCP, indexer) | `ghcr.io/abhigyanpatwari/gitnexus:latest` | `akonlabs/gitnexus:latest` |
|
||||
| Static web UI (port `4173`) | `ghcr.io/abhigyanpatwari/gitnexus-web:latest` | `akonlabs/gitnexus-web:latest` |
|
||||
| Purpose | GHCR (default in `docker-compose.yaml`) | Docker Hub mirror |
|
||||
| ---------------------------------------------------------------------- | --------------------------------------------- | ------------------------------ |
|
||||
| CLI / `gitnexus serve` backend (HTTP API on port `4747`, MCP, indexer) | `ghcr.io/abhigyanpatwari/gitnexus:latest` | `akonlabs/gitnexus:latest` |
|
||||
| Static web UI (port `4173`) | `ghcr.io/abhigyanpatwari/gitnexus-web:latest` | `akonlabs/gitnexus-web:latest` |
|
||||
|
||||
> **Heads-up — image rename.** Earlier releases published the web UI under
|
||||
> `ghcr.io/abhigyanpatwari/gitnexus`. Starting with the introduction of the
|
||||
|
|
@ -578,22 +596,22 @@ GitNexus builds a complete knowledge graph of your codebase through a multi-phas
|
|||
|
||||
### Supported Languages
|
||||
|
||||
| Language | Imports | Named Bindings | Exports | Heritage | Type Annotations | Constructor Inference | Config | Frameworks | Entry Points |
|
||||
|----------|---------|----------------|---------|----------|-----------------|---------------------|--------|------------|-------------|
|
||||
| TypeScript | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ |
|
||||
| JavaScript | ✓ | ✓ | ✓ | ✓ | — | ✓ | ✓ | ✓ | ✓ |
|
||||
| Python | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ |
|
||||
| Java | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | — | ✓ | ✓ |
|
||||
| Kotlin | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | — | ✓ | ✓ |
|
||||
| C# | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ |
|
||||
| Go | ✓ | — | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ |
|
||||
| Rust | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | — | ✓ | ✓ |
|
||||
| PHP | ✓ | ✓ | ✓ | — | ✓ | ✓ | ✓ | ✓ | ✓ |
|
||||
| Ruby | ✓ | — | ✓ | ✓ | — | ✓ | — | ✓ | ✓ |
|
||||
| Swift | — | — | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ |
|
||||
| C | — | — | ✓ | — | ✓ | ✓ | — | ✓ | ✓ |
|
||||
| C++ | — | — | ✓ | ✓ | ✓ | ✓ | — | ✓ | ✓ |
|
||||
| Dart | ✓ | — | ✓ | ✓ | ✓ | ✓ | — | ✓ | ✓ |
|
||||
| Language | Imports | Named Bindings | Exports | Heritage | Type Annotations | Constructor Inference | Config | Frameworks | Entry Points |
|
||||
| ---------- | ------- | -------------- | ------- | -------- | ---------------- | --------------------- | ------ | ---------- | ------------ |
|
||||
| TypeScript | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ |
|
||||
| JavaScript | ✓ | ✓ | ✓ | ✓ | — | ✓ | ✓ | ✓ | ✓ |
|
||||
| Python | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ |
|
||||
| Java | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | — | ✓ | ✓ |
|
||||
| Kotlin | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | — | ✓ | ✓ |
|
||||
| C# | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ |
|
||||
| Go | ✓ | — | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ |
|
||||
| Rust | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | — | ✓ | ✓ |
|
||||
| PHP | ✓ | ✓ | ✓ | — | ✓ | ✓ | ✓ | ✓ | ✓ |
|
||||
| Ruby | ✓ | — | ✓ | ✓ | — | ✓ | — | ✓ | ✓ |
|
||||
| Swift | — | — | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ |
|
||||
| C | — | — | ✓ | — | ✓ | ✓ | — | ✓ | ✓ |
|
||||
| C++ | — | — | ✓ | ✓ | ✓ | ✓ | — | ✓ | ✓ |
|
||||
| Dart | ✓ | — | ✓ | ✓ | ✓ | ✓ | — | ✓ | ✓ |
|
||||
|
||||
**Imports** — cross-file import resolution · **Named Bindings** — `import { X as Y }` / re-export tracking · **Exports** — public/exported symbol detection · **Heritage** — class inheritance, interfaces, mixins · **Type Annotations** — explicit type extraction for receiver resolution · **Constructor Inference** — infer receiver type from constructor calls (`self`/`this` resolution included for all languages) · **Config** — language toolchain config parsing (tsconfig, go.mod, etc.) · **Frameworks** — AST-based framework pattern detection · **Entry Points** — entry point scoring heuristics
|
||||
|
||||
|
|
@ -738,16 +756,16 @@ The wiki generator reads the indexed graph structure, groups files into modules
|
|||
|
||||
## Tech Stack
|
||||
|
||||
| Layer | CLI | Web |
|
||||
| ------------------------- | ------------------------------------- | --------------------------------------- |
|
||||
| Layer | CLI | Web |
|
||||
| ------------------- | ------------------------------------- | --------------------------------------- |
|
||||
| **Runtime** | Node.js (native) | Browser (WASM) |
|
||||
| **Parsing** | Tree-sitter native bindings | Tree-sitter WASM |
|
||||
| **Database** | LadybugDB native | LadybugDB WASM |
|
||||
| **Database** | LadybugDB native | LadybugDB WASM |
|
||||
| **Embeddings** | HuggingFace transformers.js (GPU/CPU) | transformers.js (WebGPU/WASM) |
|
||||
| **Search** | BM25 + semantic + RRF | BM25 + semantic + RRF |
|
||||
| **Agent Interface** | MCP (stdio) | LangChain ReAct agent |
|
||||
| **Visualization** | — | Sigma.js + Graphology (WebGL) |
|
||||
| **Frontend** | — | React 18, TypeScript, Vite, Tailwind v4 |
|
||||
| **Visualization** | — | Sigma.js + Graphology (WebGL) |
|
||||
| **Frontend** | — | React 18, TypeScript, Vite, Tailwind v4 |
|
||||
| **Clustering** | Graphology | Graphology |
|
||||
| **Concurrency** | Worker threads + async | Web Workers + Comlink |
|
||||
|
||||
|
|
@ -763,12 +781,12 @@ The wiki generator reads the indexed graph structure, groups files into modules
|
|||
|
||||
### Recently Completed
|
||||
|
||||
- [X] Constructor-Inferred Type Resolution, `self`/`this` Receiver Mapping
|
||||
- [X] Wiki Generation, Multi-File Rename, Git-Diff Impact Analysis
|
||||
- [X] Process-Grouped Search, 360-Degree Context, Claude Code Hooks
|
||||
- [X] Multi-Repo MCP, Zero-Config Setup, 14 Language Support
|
||||
- [X] Community Detection, Process Detection, Confidence Scoring
|
||||
- [X] Hybrid Search, Vector Index
|
||||
- [x] Constructor-Inferred Type Resolution, `self`/`this` Receiver Mapping
|
||||
- [x] Wiki Generation, Multi-File Rename, Git-Diff Impact Analysis
|
||||
- [x] Process-Grouped Search, 360-Degree Context, Claude Code Hooks
|
||||
- [x] Multi-Repo MCP, Zero-Config Setup, 14 Language Support
|
||||
- [x] Community Detection, Process Detection, Confidence Scoring
|
||||
- [x] Hybrid Search, Vector Index
|
||||
|
||||
---
|
||||
|
||||
|
|
|
|||
|
|
@ -211,6 +211,8 @@ environment:
|
|||
|
||||
Defaults are `port: 4848` and `host: 127.0.0.1` (loopback only). Use `0.0.0.0` only when the agent container needs to reach the eval-server from a separate network namespace. The health probe and tool scripts connect via the configured bind host (defaulting to `127.0.0.1`), which is reachable for both loopback and all-interface binds.
|
||||
|
||||
`"localhost"` is also a valid `eval_server_host` value. The OS resolves it at bind time — typically `127.0.0.1` on dual-stack or IPv4-only systems, and `::1` on IPv6-only systems. The exact result depends on your `/etc/hosts` and `gai.conf`. The READY signal will reflect the actual bound address (e.g. `GITNEXUS_EVAL_SERVER_READY:127.0.0.1:4848` or `GITNEXUS_EVAL_SERVER_READY:[::1]:4848`), not the literal string `localhost`. Use this when you want the server to bind to whichever loopback address the OS prefers rather than forcing IPv4.
|
||||
|
||||
**Running eval-server directly in Docker / Docker Compose:**
|
||||
|
||||
```bash
|
||||
|
|
|
|||
6
eval/uv.lock
generated
6
eval/uv.lock
generated
|
|
@ -760,11 +760,11 @@ wheels = [
|
|||
|
||||
[[package]]
|
||||
name = "idna"
|
||||
version = "3.11"
|
||||
version = "3.15"
|
||||
source = { registry = "https://pypi.org/simple" }
|
||||
sdist = { url = "https://files.pythonhosted.org/packages/6f/6d/0703ccc57f3a7233505399edb88de3cbd678da106337b9fcde432b65ed60/idna-3.11.tar.gz", hash = "sha256:795dafcc9c04ed0c1fb032c2aa73654d8e8c5023a7df64a53f39190ada629902", size = 194582, upload-time = "2025-10-12T14:55:20.501Z" }
|
||||
sdist = { url = "https://files.pythonhosted.org/packages/82/77/7b3966d0b9d1d31a36ddf1746926a11dface89a83409bf1483f0237aa758/idna-3.15.tar.gz", hash = "sha256:ca962446ea538f7092a95e057da437618e886f4d349216d2b1e294abfdb65fdc", size = 199245, upload-time = "2026-05-12T22:45:57.011Z" }
|
||||
wheels = [
|
||||
{ url = "https://files.pythonhosted.org/packages/0e/61/66938bbb5fc52dbdf84594873d5b51fb1f7c7794e9c0f5bd885f30bc507b/idna-3.11-py3-none-any.whl", hash = "sha256:771a87f49d9defaf64091e6e6fe9c18d4833f140bd19464795bc32d966ca37ea", size = 71008, upload-time = "2025-10-12T14:55:18.883Z" },
|
||||
{ url = "https://files.pythonhosted.org/packages/d2/23/408243171aa9aaba178d3e2559159c24c1171a641aa83b67bdd3394ead8e/idna-3.15-py3-none-any.whl", hash = "sha256:048adeaf8c2d788c40fee287673ccaa74c24ffd8dcf09ffa555a2fbb59f10ac8", size = 72340, upload-time = "2026-05-12T22:45:55.733Z" },
|
||||
]
|
||||
|
||||
[[package]]
|
||||
|
|
|
|||
|
|
@ -21,6 +21,7 @@
|
|||
* (defined in `./types.ts`).
|
||||
*/
|
||||
|
||||
import type { ParameterTypeClass } from './symbol-definition.js';
|
||||
import type { Range, ScopeId } from './types.js';
|
||||
|
||||
/**
|
||||
|
|
@ -79,4 +80,11 @@ export interface ReferenceSite {
|
|||
* (C#: `42` → `'int'`, `"alice"` → `'string'`).
|
||||
*/
|
||||
readonly argumentTypes?: readonly string[];
|
||||
/**
|
||||
* Optional per-argument type-shape sidecar for languages that need
|
||||
* cv/ref/pointer distinctions during constraint filtering. This is
|
||||
* intentionally separate from `argumentTypes`, which stays normalized
|
||||
* for existing overload narrowing and conversion-rank logic.
|
||||
*/
|
||||
readonly argumentTypeClasses?: readonly ParameterTypeClass[];
|
||||
}
|
||||
|
|
|
|||
|
|
@ -13,7 +13,7 @@
|
|||
*/
|
||||
|
||||
import type { NodeLabel } from '../../graph/types.js';
|
||||
import type { SymbolDefinition } from '../symbol-definition.js';
|
||||
import type { ParameterTypeClass, SymbolDefinition } from '../symbol-definition.js';
|
||||
import type { Callsite, DefId } from '../types.js';
|
||||
import type { DefIndex } from '../def-index.js';
|
||||
import type { QualifiedNameIndex } from '../qualified-name-index.js';
|
||||
|
|
@ -65,6 +65,13 @@ export interface ConstraintContext {
|
|||
* `narrowOverloadCandidates`' `argTypes` parameter.
|
||||
*/
|
||||
readonly argumentTypes?: readonly string[];
|
||||
/**
|
||||
* Optional shape-preserving sidecar aligned with `argumentTypes`.
|
||||
* Unknown or unsupported slots should be omitted by producers or
|
||||
* marked with `indirection: 'unknown'`; consumers must preserve the
|
||||
* monotonic fallback and return 'unknown' instead of guessing.
|
||||
*/
|
||||
readonly argumentTypeClasses?: readonly ParameterTypeClass[];
|
||||
}
|
||||
|
||||
// ─── Owner-scoped contributor (concrete shape for `RegistryContributor`) ────
|
||||
|
|
|
|||
30
gitnexus-web/package-lock.json
generated
30
gitnexus-web/package-lock.json
generated
|
|
@ -41,7 +41,7 @@
|
|||
"sigma": "^3.0.2",
|
||||
"tailwindcss": "^4.2.4",
|
||||
"uuid": "^14.0.0",
|
||||
"zod": "^3.25.76"
|
||||
"zod": "^4.3.6"
|
||||
},
|
||||
"devDependencies": {
|
||||
"@babel/types": "^7.29.0",
|
||||
|
|
@ -5599,13 +5599,12 @@
|
|||
}
|
||||
},
|
||||
"node_modules/langsmith": {
|
||||
"version": "0.5.23",
|
||||
"resolved": "https://registry.npmjs.org/langsmith/-/langsmith-0.5.23.tgz",
|
||||
"integrity": "sha512-dE/M/2Gg2S2R8ygDdkWGJVO3JstijvsNvPXsy9V8WGbpb88Zn8xF/aTjPx4mIy5gIoo02T6FssOgYyLf51Dv1Q==",
|
||||
"version": "0.6.3",
|
||||
"resolved": "https://registry.npmjs.org/langsmith/-/langsmith-0.6.3.tgz",
|
||||
"integrity": "sha512-pXrQ4/4myQvjFFOAUmt5pWRrLEZR20gzIJD7MNdUH+5/S5nLI4ZRBo/SYKC6coaYj9pYTfQdBIzcs+3kfJ5uDA==",
|
||||
"license": "MIT",
|
||||
"dependencies": {
|
||||
"p-queue": "6.6.2",
|
||||
"uuid": "10.0.0"
|
||||
"p-queue": "6.6.2"
|
||||
},
|
||||
"peerDependencies": {
|
||||
"@opentelemetry/api": "*",
|
||||
|
|
@ -5632,19 +5631,6 @@
|
|||
}
|
||||
}
|
||||
},
|
||||
"node_modules/langsmith/node_modules/uuid": {
|
||||
"version": "10.0.0",
|
||||
"resolved": "https://registry.npmjs.org/uuid/-/uuid-10.0.0.tgz",
|
||||
"integrity": "sha512-8XkAphELsDnEGrDxUOHB3RGvXz6TeuYSGEZBOjtTtPm2lwhGBjLgOzLHB63IUWfBpNucQjND6d3AOudO+H3RWQ==",
|
||||
"funding": [
|
||||
"https://github.com/sponsors/broofa",
|
||||
"https://github.com/sponsors/ctavan"
|
||||
],
|
||||
"license": "MIT",
|
||||
"bin": {
|
||||
"uuid": "dist/bin/uuid"
|
||||
}
|
||||
},
|
||||
"node_modules/layout-base": {
|
||||
"version": "1.0.2",
|
||||
"resolved": "https://registry.npmjs.org/layout-base/-/layout-base-1.0.2.tgz",
|
||||
|
|
@ -8903,9 +8889,9 @@
|
|||
}
|
||||
},
|
||||
"node_modules/zod": {
|
||||
"version": "3.25.76",
|
||||
"resolved": "https://registry.npmjs.org/zod/-/zod-3.25.76.tgz",
|
||||
"integrity": "sha512-gzUt/qt81nXsFGKIFcC3YnfEAx5NkunCfnDlvuBSSFS02bcXu4Lmea0AFIUwbLWxWPx3d9p8S5QoaujKcNQxcQ==",
|
||||
"version": "4.3.6",
|
||||
"resolved": "https://registry.npmjs.org/zod/-/zod-4.3.6.tgz",
|
||||
"integrity": "sha512-rftlrkhHZOcjDwkGlnUtZZkvaPHCsDATp4pGpuOOMDaTdDDXF91wuVDJoWoPsKX/3YPQ5fHuF3STjcYyKr+Qhg==",
|
||||
"license": "MIT",
|
||||
"funding": {
|
||||
"url": "https://github.com/sponsors/colinhacks"
|
||||
|
|
|
|||
|
|
@ -51,7 +51,7 @@
|
|||
"sigma": "^3.0.2",
|
||||
"tailwindcss": "^4.2.4",
|
||||
"uuid": "^14.0.0",
|
||||
"zod": "^3.25.76"
|
||||
"zod": "^4.3.6"
|
||||
},
|
||||
"devDependencies": {
|
||||
"@babel/types": "^7.29.0",
|
||||
|
|
|
|||
|
|
@ -151,7 +151,8 @@ Your AI agent gets these tools automatically:
|
|||
```bash
|
||||
gitnexus setup # Configure MCP for your editors (one-time)
|
||||
gitnexus analyze [path] # Index a repository (or update stale index)
|
||||
gitnexus analyze --force # Force full re-index
|
||||
gitnexus analyze --repair-fts # Fast path: rebuild/verify only FTS indexes on existing index data
|
||||
gitnexus analyze --force # Full rebuild: re-parse + graph rebuild + FTS rebuild
|
||||
gitnexus analyze --embeddings # Enable embedding generation (slower, better search)
|
||||
gitnexus analyze --skip-agents-md # Preserve custom AGENTS.md/CLAUDE.md gitnexus section edits
|
||||
gitnexus analyze --verbose # Log skipped files when parsers are unavailable
|
||||
|
|
@ -358,6 +359,16 @@ npx gitnexus analyze
|
|||
|
||||
For repositories with very large source files, `GITNEXUS_WORKER_SUB_BATCH_MAX_BYTES` controls the worker job byte budget. The default is **8388608 bytes (8 MB)**.
|
||||
|
||||
### Worker pool resilience tuning
|
||||
|
||||
Three env vars expose the pool's resilience layers (respawn budget, cumulative-timeout cap, circuit breaker). Defaults are tuned for typical repos; bump them when an analyze legitimately needs more retries, or lower them to fail-fast on a known-bad shape.
|
||||
|
||||
| Variable | Default | Effect |
|
||||
| ------------------------------------------------- | ------------------------- | --------------------------------------------------------------------------------------------------------------------------------- |
|
||||
| `GITNEXUS_WORKER_MAX_RESPAWNS_PER_SLOT` | `3` | Max replacement spawns per slot before the slot is dropped from the active rotation. |
|
||||
| `GITNEXUS_WORKER_MAX_CUMULATIVE_TIMEOUT_MS` | `5 × subBatchTimeoutMs` | Total retry wall-time budget per job before quarantining. Bounds exponentially-growing retry waits. |
|
||||
| `GITNEXUS_WORKER_CONSECUTIVE_FAILURE_THRESHOLD` | `max(3, poolSize)` | Per-slot consecutive deaths before the pool's circuit breaker trips. After tripping, dispatches require a fresh pool. |
|
||||
|
||||
## Privacy
|
||||
|
||||
- All processing happens locally on your machine
|
||||
|
|
|
|||
175
gitnexus/bench/parse-throughput.md
Normal file
175
gitnexus/bench/parse-throughput.md
Normal file
|
|
@ -0,0 +1,175 @@
|
|||
# Parse-throughput benchmark (scaffold)
|
||||
|
||||
> **Status: methodology + harness scaffold, no measurement data yet.**
|
||||
> The Latest measurement table below contains `_TBD_` placeholders.
|
||||
> This file ships intentionally without numbers — populating it
|
||||
> requires a dedicated bench-pass against the U6 fixture (and ideally
|
||||
> a real-world TS-root-scale repo) on consistent hardware, which is
|
||||
> tracked as future work rather than gated on PR #1693's merge.
|
||||
> Until the table is populated, the load-bearing perf-regression
|
||||
> protection lives in `gitnexus/test/integration/parse-impl-large-fixture.test.ts`
|
||||
> (U6, 30 s wall-clock budget via `Promise.race`).
|
||||
|
||||
Tracks `runChunkedParseAndResolve` wall-clock + peak heap on a synthetic
|
||||
fixture so PR #1693's "analyze no longer hangs on TS-root-shaped loads"
|
||||
claim is measurable, not just asserted by smoke tests. The harness
|
||||
recipe below is deliberately small enough to re-run in a few minutes
|
||||
when the bench-pass is undertaken.
|
||||
|
||||
---
|
||||
|
||||
## Methodology
|
||||
|
||||
### Fixture
|
||||
|
||||
Synthetic TypeScript repo, _not_ a clone of microsoft/TypeScript. CI cost
|
||||
of cloning real-world repos is prohibitive; the synthetic shape exercises
|
||||
the same pipeline paths (chunking, deferred extraction, cross-chunk
|
||||
imports + heritage) without the disk-I/O overhead. Larger numbers can be
|
||||
manually captured against real repos and cross-referenced here, but the
|
||||
authoritative regression-tracking shape is the synthetic fixture so runs
|
||||
are reproducible across hardware.
|
||||
|
||||
The fixture matches the structure pinned by
|
||||
`gitnexus/test/integration/parse-impl-large-fixture.test.ts` (U6):
|
||||
|
||||
- 15 small modules (`mod0.ts` … `mod14.ts`), one exported function each.
|
||||
- 1 dense `complex.ts` with 30 functions + 1 class + 1 interface.
|
||||
- 1 `index.ts` re-exporting every symbol from every module.
|
||||
|
||||
`GITNEXUS_CHUNK_BYTE_BUDGET=64` forces multi-chunk parsing on this small
|
||||
fixture — without that override the whole thing fits in one chunk and
|
||||
the deferred-extraction path is not exercised end-to-end.
|
||||
|
||||
### What to measure
|
||||
|
||||
| Metric | How |
|
||||
| --------------------------- | -------------------------------------------------------------------------------- |
|
||||
| Wall-clock total | `Date.now()` delta around `runChunkedParseAndResolve` |
|
||||
| Peak heap | Sample `process.memoryUsage().heapUsed` every 50 ms during the run; keep the max |
|
||||
| Chunks observed | Count distinct `Parsing chunk X/Y` progress messages |
|
||||
| `getStats()` final snapshot | Quarantined paths, dropped slots, breaker state |
|
||||
|
||||
### Hardware shape (record alongside each measurement)
|
||||
|
||||
- OS + version
|
||||
- CPU model + logical core count
|
||||
- RAM
|
||||
- Node version
|
||||
- gitnexus commit SHA (so the snapshot is anchored to a tree, not "main")
|
||||
|
||||
---
|
||||
|
||||
## Harness recipe
|
||||
|
||||
The U6 test (`test/integration/parse-impl-large-fixture.test.ts`) is the
|
||||
checked-in mini-benchmark — it exercises the same fixture and bounds the
|
||||
wall-clock at 30 s via `Promise.race`. To produce a richer snapshot for
|
||||
this doc, run it under instrumentation:
|
||||
|
||||
```bash
|
||||
# From the gitnexus/ subdir:
|
||||
cd gitnexus
|
||||
# Single-threaded baseline (sequential fallback):
|
||||
npx vitest run test/integration/parse-impl-large-fixture.test.ts --reporter=verbose
|
||||
|
||||
# Worker-pool path (requires built dist/ — pre-built by `npm run build`):
|
||||
npm run build && \
|
||||
GITNEXUS_WORKER_POOL_SIZE=4 \
|
||||
GITNEXUS_PARSE_CHUNK_CONCURRENCY=2 \
|
||||
GITNEXUS_VERBOSE=1 \
|
||||
npx vitest run test/integration/parse-impl-large-fixture.test.ts --reporter=verbose
|
||||
```
|
||||
|
||||
For peak-heap sampling, wrap the dispatch call in a Node script that
|
||||
polls `process.memoryUsage()`. A future helper at
|
||||
`gitnexus/bench/scripts/parse-throughput.ts` would automate this — the
|
||||
plan's stretch goal. Until that lands, capture peak heap manually via:
|
||||
|
||||
```bash
|
||||
node --inspect=0 \
|
||||
--require ./scripts/heap-sampler.js \
|
||||
./node_modules/.bin/vitest run test/integration/parse-impl-large-fixture.test.ts
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Latest measurement
|
||||
|
||||
> _No measurement data has been collected yet — this file is the
|
||||
> methodology + harness scaffold. The single recorded data point is the
|
||||
> U6 wall-clock smoke baseline below; the worker-pool rows are
|
||||
> placeholders for future bench-pass output._
|
||||
|
||||
The U6 integration test (`gitnexus/test/integration/parse-impl-large-fixture.test.ts`)
|
||||
was observed completing the synthetic fixture in **~6 seconds** under
|
||||
the sequential path (`skipWorkers: true`) on the development machine,
|
||||
well under the 30 s `Promise.race` wall-clock budget. That number is a
|
||||
smoke baseline only — recorded here for reference, not as a regression
|
||||
target.
|
||||
|
||||
| Path | files/s | wall-clock | peak heap | chunks | quarantined |
|
||||
| ------------------------------------------ | ------- | -------------------- | --------- | ------ | ----------- |
|
||||
| Sequential (`skipWorkers: true`, U6 smoke) | _TBD_ | ~6 s _(observation)_ | _TBD_ | 17 | 0 |
|
||||
| Worker pool, `--workers 4`, concurrency 2 | _TBD_ | _TBD_ | _TBD_ | _TBD_ | 0 |
|
||||
| Worker pool, `--workers 1`, concurrency 1 | _TBD_ | _TBD_ | _TBD_ | _TBD_ | 0 |
|
||||
|
||||
**Hardware:** _TBD — record OS, CPU, RAM, Node version, gitnexus SHA at
|
||||
the time of the bench-pass that populates the table above._
|
||||
|
||||
---
|
||||
|
||||
## Operator-tuning quick reference
|
||||
|
||||
Cross-links to the env vars documented in the [README](../../README.md#environment-variables).
|
||||
Use this section as a starting point when the benchmark numbers above
|
||||
suggest a tuning opportunity for your hardware shape.
|
||||
|
||||
- **CPU-bound, big repo, lots of cores:** raise `GITNEXUS_WORKER_POOL_SIZE`
|
||||
past the default cap of 16. The 16-worker cap exists because past that
|
||||
point main-thread merge / extraction dominates; if you've measurably
|
||||
ruled that out, the env var lifts the cap explicitly. (See
|
||||
`worker-pool.ts` `DEFAULT_POOL_SIZE_CAP`.)
|
||||
- **Slow files (large minified JS, deep TS types):** raise
|
||||
`GITNEXUS_WORKER_SUB_BATCH_TIMEOUT_MS` past 30 000 ms. The cumulative
|
||||
budget is 5× this value (U10 pins this) so a 60 s idle timeout permits
|
||||
300 s of total retry-and-split wall-clock before quarantining the file.
|
||||
- **Constrained container (cgroup CPU limit):** the pool now uses
|
||||
`os.availableParallelism()` (U3 H2), which honors cgroup limits — no
|
||||
manual `GITNEXUS_WORKER_POOL_SIZE` override needed unless the auto-
|
||||
resolved value is too aggressive for your I/O budget.
|
||||
- **Long-running host (eval-server, MCP daemon) running back-to-back
|
||||
analyzes:** `--workers` is now threaded through `AnalyzeOptions`
|
||||
(U2 B2), so per-invocation sizing is honored without `process.env`
|
||||
state leaking across calls. `GITNEXUS_VERBOSE` is similarly snapshot/
|
||||
restore-bracketed.
|
||||
|
||||
---
|
||||
|
||||
## What this benchmark does NOT measure
|
||||
|
||||
- **Real-repo performance.** The synthetic fixture is sized for CI; it
|
||||
doesn't exercise the cumulative-load shape (50k files, occasional
|
||||
pathological file) that drove the original PR #1693 hang report. Real-
|
||||
repo numbers should be captured ad-hoc against the user's target repo
|
||||
and cross-referenced here only as supplementary evidence.
|
||||
- **Worker-pool resilience under real crashes.** That's verified by the
|
||||
`worker-pool.test.ts` integration tests (real `process.exit`, real
|
||||
`error` events, real protocol violations) and the unit suite. The
|
||||
benchmark cares about throughput on the happy path.
|
||||
- **IPC repack throughput.** Phase 3 of the PR #1693 plan introduces a
|
||||
transferList + binary wire-format IPC repack (U16-U17). Once that
|
||||
lands, an `IPC repack` row should be added to the "Latest measurement"
|
||||
table above with before/after numbers on the same hardware.
|
||||
|
||||
---
|
||||
|
||||
## Related artifacts
|
||||
|
||||
- Plan: `docs/plans/2026-05-20-001-feat-pr1693-resilience-hardening-and-ipc-repack-plan.md`
|
||||
- Integration test (mini-benchmark with wall-clock guard): `gitnexus/test/integration/parse-impl-large-fixture.test.ts` (U6)
|
||||
- Operator env-var reference: `README.md` → Environment variables
|
||||
- Resilience layer tests: `gitnexus/test/unit/worker-pool-resilience.test.ts`,
|
||||
`worker-pool-cumulative-timeout.test.ts`,
|
||||
`worker-pool-windows-quarantine.test.ts`,
|
||||
`worker-pool-slot-generation.test.ts`
|
||||
844
gitnexus/package-lock.json
generated
844
gitnexus/package-lock.json
generated
File diff suppressed because it is too large
Load diff
|
|
@ -60,7 +60,7 @@
|
|||
"cli-progress": "^3.12.0",
|
||||
"commander": "^14.0.3",
|
||||
"cors": "^2.8.5",
|
||||
"express": "^4.19.2",
|
||||
"express": "^5.2.1",
|
||||
"express-rate-limit": "^8.4.1",
|
||||
"glob": "^13.0.6",
|
||||
"graphology": "^0.26.0",
|
||||
|
|
@ -100,7 +100,7 @@
|
|||
"devDependencies": {
|
||||
"@types/cli-progress": "^3.11.6",
|
||||
"@types/cors": "^2.8.17",
|
||||
"@types/express": "^4.17.21",
|
||||
"@types/express": "^5.0.6",
|
||||
"@types/js-yaml": "^4.0.9",
|
||||
"@types/node": "^25.6.0",
|
||||
"@types/uuid": "^11.0.0",
|
||||
|
|
|
|||
|
|
@ -148,7 +148,7 @@ function ensureHeap(): boolean {
|
|||
stdio: 'inherit',
|
||||
env: { ...process.env, NODE_OPTIONS: `${nodeOpts} ${HEAP_FLAG}`.trim() },
|
||||
});
|
||||
} catch (e: any) {
|
||||
} catch (e: unknown) {
|
||||
if (childProcessLikelyOom(e)) {
|
||||
cliError(
|
||||
` Analysis likely ran out of memory.\n` +
|
||||
|
|
@ -159,13 +159,53 @@ function ensureHeap(): boolean {
|
|||
{ recoveryHint: 'heap-oom-respawn' },
|
||||
);
|
||||
}
|
||||
process.exitCode = e.status ?? 1;
|
||||
const status =
|
||||
typeof e === 'object' && e !== null && 'status' in e && typeof e.status === 'number'
|
||||
? e.status
|
||||
: 1;
|
||||
process.exitCode = status;
|
||||
}
|
||||
return true;
|
||||
}
|
||||
|
||||
/**
|
||||
* GITNEXUS_* env vars that `analyzeCommand` writes for backward-compatible
|
||||
* downstream consumption. Snapshotted at function entry and restored in the
|
||||
* finally block so that programmatic callers (tests, long-running hosts)
|
||||
* don't see leaked state across invocations. `GITNEXUS_WORKER_POOL_SIZE` is
|
||||
* NOT in this list: that knob is threaded through `runFullAnalysis` options
|
||||
* (see `workerPoolSize` plumbing) so the CLI never has to mutate `process.env`
|
||||
* for it in the first place.
|
||||
*/
|
||||
const ANALYZE_CLI_ENV_KEYS = [
|
||||
'GITNEXUS_VERBOSE',
|
||||
'GITNEXUS_MAX_FILE_SIZE',
|
||||
'GITNEXUS_WORKER_SUB_BATCH_TIMEOUT_MS',
|
||||
'GITNEXUS_EMBEDDING_THREADS',
|
||||
'GITNEXUS_EMBEDDING_BATCH_SIZE',
|
||||
'GITNEXUS_EMBEDDING_SUB_BATCH_SIZE',
|
||||
'GITNEXUS_EMBEDDING_DEVICE',
|
||||
] as const;
|
||||
|
||||
type AnalyzeEnvSnapshot = Record<(typeof ANALYZE_CLI_ENV_KEYS)[number], string | undefined>;
|
||||
|
||||
const snapshotAnalyzeEnv = (): AnalyzeEnvSnapshot => {
|
||||
const snap = {} as AnalyzeEnvSnapshot;
|
||||
for (const k of ANALYZE_CLI_ENV_KEYS) snap[k] = process.env[k];
|
||||
return snap;
|
||||
};
|
||||
|
||||
const restoreAnalyzeEnv = (snap: AnalyzeEnvSnapshot): void => {
|
||||
for (const k of ANALYZE_CLI_ENV_KEYS) {
|
||||
const v = snap[k];
|
||||
if (v === undefined) delete process.env[k];
|
||||
else process.env[k] = v;
|
||||
}
|
||||
};
|
||||
|
||||
export interface AnalyzeOptions {
|
||||
force?: boolean;
|
||||
repairFts?: boolean;
|
||||
/**
|
||||
* Embedding generation toggle. Commander parses `--embeddings [limit]` as:
|
||||
* - `undefined` when the flag is omitted
|
||||
|
|
@ -225,6 +265,8 @@ export interface AnalyzeOptions {
|
|||
maxFileSize?: string;
|
||||
/** Override worker sub-batch idle timeout in seconds. */
|
||||
workerTimeout?: string;
|
||||
/** Parse worker pool size; 0 disables workers (sequential fallback). */
|
||||
workers?: string;
|
||||
embeddingThreads?: string;
|
||||
embeddingBatchSize?: string;
|
||||
embeddingSubBatchSize?: string;
|
||||
|
|
@ -258,6 +300,22 @@ export const analyzeCommand = async (inputPath?: string, options?: AnalyzeOption
|
|||
// a stack trace and a non-zero exit code instead of a silent exit 0.
|
||||
installFatalHandlers();
|
||||
|
||||
// Snapshot the GITNEXUS_* env vars that the impl writes for downstream
|
||||
// consumption, so they don't leak across `analyzeCommand` invocations in
|
||||
// programmatic callers (tests, long-running hosts). `process.exit(0)` on
|
||||
// the success path bypasses `finally` — intentional: when the process is
|
||||
// exiting, restoration is moot. For early-return paths (validation
|
||||
// errors) and the alreadyUpToDate fast path the finally restores the
|
||||
// pre-call values.
|
||||
const envSnap = snapshotAnalyzeEnv();
|
||||
try {
|
||||
await analyzeCommandImpl(inputPath, options);
|
||||
} finally {
|
||||
restoreAnalyzeEnv(envSnap);
|
||||
}
|
||||
};
|
||||
|
||||
const analyzeCommandImpl = async (inputPath?: string, options?: AnalyzeOptions): Promise<void> => {
|
||||
if (options?.verbose) {
|
||||
process.env.GITNEXUS_VERBOSE = '1';
|
||||
}
|
||||
|
|
@ -278,6 +336,26 @@ export const analyzeCommand = async (inputPath?: string, options?: AnalyzeOption
|
|||
);
|
||||
}
|
||||
|
||||
// `--workers` is threaded through `runFullAnalysis` options → PipelineOptions
|
||||
// → createWorkerPool, intentionally bypassing the GITNEXUS_WORKER_POOL_SIZE
|
||||
// env channel so this CLI surface never mutates `process.env` for pool size.
|
||||
// Tests can therefore re-invoke analyzeCommand with different --workers
|
||||
// values back-to-back and observe the value they passed, not whatever the
|
||||
// previous call leaked.
|
||||
let workerPoolSize: number | undefined;
|
||||
if (options?.workers !== undefined) {
|
||||
const parsedWorkers = Number(options.workers);
|
||||
if (!Number.isInteger(parsedWorkers) || parsedWorkers < 0) {
|
||||
cliError(
|
||||
' --workers must be a non-negative integer. ' +
|
||||
'Pass 0 to disable the worker pool (sequential fallback).\n',
|
||||
);
|
||||
process.exitCode = 1;
|
||||
return;
|
||||
}
|
||||
workerPoolSize = parsedWorkers;
|
||||
}
|
||||
|
||||
// Parse `--embeddings [limit]`: `true` → default cap, string → numeric cap
|
||||
// (0 disables the cap entirely). Validated up here so failures match the
|
||||
// sibling-validation pattern (exit before bar.start() — otherwise
|
||||
|
|
@ -343,6 +421,15 @@ export const analyzeCommand = async (inputPath?: string, options?: AnalyzeOption
|
|||
process.env.GITNEXUS_EMBEDDING_DEVICE = options.embeddingDevice;
|
||||
}
|
||||
|
||||
if (options?.repairFts && options?.force) {
|
||||
cliError(
|
||||
' Cannot combine `--repair-fts` with `--force`. ' +
|
||||
'Use `--repair-fts` for fast FTS-only repair, or `--force` for a full rebuild.\n',
|
||||
);
|
||||
process.exitCode = 1;
|
||||
return;
|
||||
}
|
||||
|
||||
console.log('\n GitNexus Analyzer\n');
|
||||
|
||||
// `--index-only` is the stronger contract — it suppresses every form of file
|
||||
|
|
@ -521,9 +608,11 @@ export const analyzeCommand = async (inputPath?: string, options?: AnalyzeOption
|
|||
// needs a fresh pipelineResult. Has no bearing on the registry
|
||||
// collision guard (see allowDuplicateName below).
|
||||
force: options?.force || options?.skills,
|
||||
repairFts: options?.repairFts,
|
||||
embeddings: embeddingsEnabled,
|
||||
embeddingsNodeLimit,
|
||||
dropEmbeddings: options?.dropEmbeddings,
|
||||
verbose: options?.verbose,
|
||||
skipGit: options?.skipGit,
|
||||
skipAgentsMd,
|
||||
skipSkills,
|
||||
|
|
@ -539,6 +628,10 @@ export const analyzeCommand = async (inputPath?: string, options?: AnalyzeOption
|
|||
// be able to accept the duplicate name without also paying the
|
||||
// cost of a full pipeline re-index. See #829 review round 2.
|
||||
allowDuplicateName: options?.allowDuplicateName,
|
||||
// Worker pool size threaded from --workers, replacing the previous
|
||||
// GITNEXUS_WORKER_POOL_SIZE env mutation. `undefined` defers to the
|
||||
// env / auto-formula fallback inside the pipeline.
|
||||
workerPoolSize,
|
||||
},
|
||||
{
|
||||
onProgress: (_phase, percent, message) => {
|
||||
|
|
@ -568,6 +661,19 @@ export const analyzeCommand = async (inputPath?: string, options?: AnalyzeOption
|
|||
return;
|
||||
}
|
||||
|
||||
if (result.ftsRepairedOnly) {
|
||||
clearInterval(elapsedTimer);
|
||||
process.removeListener('SIGINT', sigintHandler);
|
||||
console.log = origLog;
|
||||
// eslint-disable-next-line no-console -- restoring after intentional progress-bar routing
|
||||
console.warn = origWarn;
|
||||
// eslint-disable-next-line no-console -- restoring after intentional progress-bar routing
|
||||
console.error = origError;
|
||||
bar.stop();
|
||||
console.log(' FTS indexes repaired successfully\n');
|
||||
return;
|
||||
}
|
||||
|
||||
// Post-finalize invariant (#1169): runFullAnalysis nominally writes
|
||||
// meta.json and registers the repo, but on Windows it has been
|
||||
// observed to return successfully with neither artifact present
|
||||
|
|
@ -663,7 +769,7 @@ export const analyzeCommand = async (inputPath?: string, options?: AnalyzeOption
|
|||
}
|
||||
|
||||
console.log('');
|
||||
} catch (err: any) {
|
||||
} catch (err: unknown) {
|
||||
clearInterval(elapsedTimer);
|
||||
process.removeListener('SIGINT', sigintHandler);
|
||||
console.log = origLog;
|
||||
|
|
@ -673,7 +779,7 @@ export const analyzeCommand = async (inputPath?: string, options?: AnalyzeOption
|
|||
console.error = origError;
|
||||
bar.stop();
|
||||
|
||||
const msg = err.message || String(err);
|
||||
const msg = err instanceof Error ? err.message : String(err);
|
||||
|
||||
// Registry name-collision from --name (#829) — surface as an
|
||||
// actionable error rather than a generic stack-trace.
|
||||
|
|
|
|||
|
|
@ -44,10 +44,12 @@ export interface EvalServerOptions {
|
|||
|
||||
/**
|
||||
* Validate the --host value. Accepts IPv4, IPv6, or "localhost".
|
||||
* Returns the normalised host string, or null if invalid.
|
||||
* Returns the host string unchanged, or null if invalid.
|
||||
* "localhost" is passed through so the OS resolves it to the correct loopback
|
||||
* address (127.0.0.1 or ::1) at bind time rather than forcing IPv4.
|
||||
*/
|
||||
export function validateHost(raw: string): string | null {
|
||||
if (raw === 'localhost') return '127.0.0.1';
|
||||
if (raw === 'localhost') return raw;
|
||||
if (isIPv4(raw) || isIPv6(raw)) return raw;
|
||||
return null;
|
||||
}
|
||||
|
|
@ -470,12 +472,14 @@ export async function evalServerCommand(options?: EvalServerOptions): Promise<vo
|
|||
{ code: err.code, port, host },
|
||||
);
|
||||
} else if (err.code === 'EADDRNOTAVAIL') {
|
||||
const isIPv6Host = isIPv6(host);
|
||||
// "localhost" may resolve to ::1 on IPv6-only systems; treat it as
|
||||
// potentially IPv6 so the user gets the right diagnostic hint.
|
||||
const isIPv6Host = isIPv6(host) || host === 'localhost';
|
||||
cliError(
|
||||
`\nGitNexus eval-server failed to start:\n` +
|
||||
` Address ${host} is not available on this machine.\n\n` +
|
||||
(isIPv6Host
|
||||
? ` IPv6 address ${host} is not reachable — IPv6 may be disabled on this system or container.\n` +
|
||||
? ` Address ${host} resolved but is not reachable — IPv6 may be disabled, or the loopback interface may be unavailable.\n` +
|
||||
` Docker containers and many CI environments disable IPv6 by default.\n\n`
|
||||
: ` The --host value must be an IP assigned to a local network interface.\n` +
|
||||
` Run \`ip addr\` (Linux) or \`ipconfig\` (Windows) to list available addresses.\n\n`) +
|
||||
|
|
@ -506,10 +510,21 @@ export async function evalServerCommand(options?: EvalServerOptions): Promise<vo
|
|||
// Plain-text banner for the human watching stderr; structured record
|
||||
// for log aggregation (split into two so the user sees a real banner
|
||||
// not `{"level":30,"msg":"...","port":4747,"endpoints":[...]}`).
|
||||
// Use server.address().port so --port 0 (OS-assigned) emits the real port.
|
||||
// Use server.address() so the banner and READY signal reflect what the OS
|
||||
// actually bound to, not the input host string. This matters when "localhost"
|
||||
// is passed: the OS may resolve it to ::1 on some systems.
|
||||
const addr = server.address();
|
||||
const boundPort = typeof addr === 'object' && addr !== null ? addr.port : port;
|
||||
const displayHost = host.includes(':') ? `[${host}]` : host;
|
||||
// server.listen callback only fires after a successful TCP bind, so
|
||||
// server.address() is guaranteed to return an AddressInfo object here.
|
||||
if (typeof addr !== 'object' || addr === null) {
|
||||
cliError(
|
||||
`\nGitNexus eval-server: unexpected server.address() value after bind: ${JSON.stringify(addr)}\n`,
|
||||
);
|
||||
process.exit(1);
|
||||
}
|
||||
const boundPort = addr.port;
|
||||
const boundAddress = addr.address;
|
||||
const displayHost = boundAddress.includes(':') ? `[${boundAddress}]` : boundAddress;
|
||||
const bannerLines = [
|
||||
`GitNexus eval-server: listening on http://${displayHost}:${boundPort}`,
|
||||
` POST /tool/query — search execution flows`,
|
||||
|
|
@ -537,8 +552,7 @@ export async function evalServerCommand(options?: EvalServerOptions): Promise<vo
|
|||
});
|
||||
try {
|
||||
// Use fd 1 directly — LadybugDB captures process.stdout (#324)
|
||||
const readyHost = host.includes(':') ? `[${host}]` : host;
|
||||
writeSync(1, `GITNEXUS_EVAL_SERVER_READY:${readyHost}:${boundPort}\n`);
|
||||
writeSync(1, `GITNEXUS_EVAL_SERVER_READY:${displayHost}:${boundPort}\n`);
|
||||
} catch {
|
||||
// stdout may not be available (e.g., broken pipe)
|
||||
}
|
||||
|
|
|
|||
|
|
@ -23,6 +23,7 @@ program
|
|||
.command('analyze [path]')
|
||||
.description('Index a repository (full analysis)')
|
||||
.option('-f, --force', 'Force full re-index even if up to date')
|
||||
.option('--repair-fts', 'Repair/rebuild search FTS indexes without full re-analysis')
|
||||
.option(
|
||||
'--embeddings [limit]',
|
||||
'Enable embedding generation for semantic search (off by default). ' +
|
||||
|
|
@ -70,6 +71,10 @@ program
|
|||
'--worker-timeout <seconds>',
|
||||
'Worker sub-batch idle timeout before retry/fallback. Default: 30.',
|
||||
)
|
||||
.option(
|
||||
'--workers <n>',
|
||||
'Parse worker pool size. Default: cores-1 capped at 16. Pass 0 to disable workers (sequential).',
|
||||
)
|
||||
.option('--embedding-threads <n>', 'Limit local ONNX embedding CPU threads')
|
||||
.option('--embedding-batch-size <n>', 'Number of nodes per embedding batch')
|
||||
.option('--embedding-sub-batch-size <n>', 'Number of chunks per embedding model call')
|
||||
|
|
@ -81,6 +86,11 @@ program
|
|||
' GITNEXUS_MAX_FILE_SIZE=N Override large-file skip threshold (KB). Default 512, max 32768.\n' +
|
||||
' GITNEXUS_WORKER_SUB_BATCH_TIMEOUT_MS=N Worker idle timeout in milliseconds. Default 30000.\n' +
|
||||
' GITNEXUS_WORKER_SUB_BATCH_MAX_BYTES=N Worker job byte budget. Default 8388608.\n' +
|
||||
' GITNEXUS_WORKER_POOL_SIZE=N Parse worker count override. Default cores-1 capped at 16.\n' +
|
||||
' GITNEXUS_PARSE_CHUNK_CONCURRENCY=N Concurrent in-flight parse chunks. Default 2.\n' +
|
||||
' GITNEXUS_WORKER_MAX_RESPAWNS_PER_SLOT=N Max replacement spawns per slot before drop. Default 3.\n' +
|
||||
' GITNEXUS_WORKER_MAX_CUMULATIVE_TIMEOUT_MS=N Total retry wall-time per job. Default 5x sub-batch timeout.\n' +
|
||||
' GITNEXUS_WORKER_CONSECUTIVE_FAILURE_THRESHOLD=N Per-slot deaths to trip circuit breaker. Default max(3, poolSize).\n' +
|
||||
' GITNEXUS_EMBEDDING_THREADS=N Limit local ONNX CPU threads for --embeddings.\n' +
|
||||
' GITNEXUS_SEMANTIC_EXACT_SCAN_LIMIT=N Max embedding chunks for exact-scan fallback. Default 10000.\n' +
|
||||
'\nTip: `.gitnexusignore` supports `.gitignore`-style negation. Add e.g.\n' +
|
||||
|
|
|
|||
|
|
@ -61,11 +61,13 @@ function resolveGitnexusBin(): string | null {
|
|||
.filter(Boolean);
|
||||
|
||||
if (isWin) {
|
||||
// On Windows, `where` returns multiple entries (e.g. the POSIX shell
|
||||
// script AND the .cmd/.bat wrapper). Prefer the wrapper because
|
||||
// child_process.spawn() cannot execute a shell script directly.
|
||||
// On Windows, npm global installs can surface multiple launchers for the
|
||||
// same package (e.g. a POSIX shell shim plus .cmd/.bat wrappers). Claude
|
||||
// and the other MCP hosts need a directly spawnable command path, so only
|
||||
// accept the Windows wrapper. If it is missing, fall back to the slower
|
||||
// npx entry instead of persisting a non-spawnable shim path.
|
||||
const cmdLine = lines.find((l) => /\.(cmd|bat)$/i.test(l));
|
||||
return cmdLine || lines[0] || null;
|
||||
return cmdLine || null;
|
||||
}
|
||||
|
||||
return lines[0] || null;
|
||||
|
|
|
|||
|
|
@ -107,6 +107,24 @@ function prompt(question: string, hide = false): Promise<string> {
|
|||
}
|
||||
|
||||
export const wikiCommand = async (inputPath?: string, options?: WikiCommandOptions) => {
|
||||
// Snapshot GITNEXUS_VERBOSE at entry — wikiCommand mutates it (the impl
|
||||
// below) so cursor-client (process.env-driven) sees the right value during
|
||||
// this run. Restored in finally so back-to-back wiki calls in long-running
|
||||
// hosts don't leak verbose state from one invocation to the next. Pairs
|
||||
// with the same snapshot/restore pattern in `analyzeCommand`.
|
||||
const originalVerbose = process.env.GITNEXUS_VERBOSE;
|
||||
try {
|
||||
await wikiCommandImpl(inputPath, options);
|
||||
} finally {
|
||||
if (originalVerbose === undefined) {
|
||||
delete process.env.GITNEXUS_VERBOSE;
|
||||
} else {
|
||||
process.env.GITNEXUS_VERBOSE = originalVerbose;
|
||||
}
|
||||
}
|
||||
};
|
||||
|
||||
const wikiCommandImpl = async (inputPath?: string, options?: WikiCommandOptions): Promise<void> => {
|
||||
// Set verbose mode globally for cursor-client to pick up
|
||||
if (options?.verbose) {
|
||||
process.env.GITNEXUS_VERBOSE = '1';
|
||||
|
|
|
|||
|
|
@ -18,12 +18,14 @@ import { getPluginForFile, HTTP_SCAN_GLOB, type HttpDetection } from './http-pat
|
|||
* the preferred path because the graph has richer symbol metadata
|
||||
* (real uids, class/method structure, etc.).
|
||||
*
|
||||
* 2. **Source-scan fallback (Strategy B)** — parse files directly with
|
||||
* the per-language plugin registry in `./http-patterns/`. Used when
|
||||
* the graph has no routes/fetches for this repo (e.g. a repo that
|
||||
* hasn't been indexed yet, or whose indexer doesn't know the
|
||||
* framework). Each plugin owns its tree-sitter grammar and query
|
||||
* sources — this orchestrator imports NO grammars or query strings.
|
||||
* 2. **Source-scan supplement (Strategy B)** — parse files directly with
|
||||
* the per-language plugin registry in `./http-patterns/`. Used to
|
||||
* fill gaps when graph extraction only covers part of a polyglot repo
|
||||
* (e.g. Java graph routes plus Go source-scan routes). Graph entries
|
||||
* remain authoritative for duplicate contract IDs because they carry
|
||||
* richer symbol metadata. Each plugin owns its tree-sitter grammar
|
||||
* and query sources — this orchestrator imports NO grammars or query
|
||||
* strings.
|
||||
*
|
||||
* Adding a new language for Strategy B is a one-file edit in
|
||||
* `http-patterns/index.ts`: register a new `HttpLanguagePlugin` and
|
||||
|
|
@ -194,17 +196,19 @@ export class HttpRouteExtractor implements ContractExtractor {
|
|||
|
||||
const graphProviders =
|
||||
dbExecutor != null ? await this.extractProvidersGraph(dbExecutor, getDetections) : [];
|
||||
const providers =
|
||||
graphProviders.length > 0
|
||||
? graphProviders
|
||||
: this.extractProvidersSourceScan(await getScannedFiles(), getDetections);
|
||||
// Source scan always runs to capture routes in languages/files not covered
|
||||
// by graph edges; the glob and per-file parse results are cached above.
|
||||
const providers = this.mergeGraphAndSourceContracts(
|
||||
graphProviders,
|
||||
this.extractProvidersSourceScan(await getScannedFiles(), getDetections),
|
||||
);
|
||||
|
||||
const graphConsumers =
|
||||
dbExecutor != null ? await this.extractConsumersGraph(dbExecutor, getDetections) : [];
|
||||
const consumers =
|
||||
graphConsumers.length > 0
|
||||
? graphConsumers
|
||||
: this.extractConsumersSourceScan(await getScannedFiles(), getDetections);
|
||||
const consumers = this.mergeGraphAndSourceContracts(
|
||||
graphConsumers,
|
||||
this.extractConsumersSourceScan(await getScannedFiles(), getDetections),
|
||||
);
|
||||
|
||||
return [...providers, ...consumers];
|
||||
}
|
||||
|
|
@ -473,4 +477,18 @@ export class HttpRouteExtractor implements ContractExtractor {
|
|||
}
|
||||
return out;
|
||||
}
|
||||
|
||||
private mergeGraphAndSourceContracts(
|
||||
graphContracts: ExtractedContract[],
|
||||
sourceContracts: ExtractedContract[],
|
||||
): ExtractedContract[] {
|
||||
const seenContractIds = new Set(graphContracts.map((c) => c.contractId));
|
||||
const out = [...graphContracts];
|
||||
for (const contract of sourceContracts) {
|
||||
if (seenContractIds.has(contract.contractId)) continue;
|
||||
seenContractIds.add(contract.contractId);
|
||||
out.push(contract);
|
||||
}
|
||||
return out;
|
||||
}
|
||||
}
|
||||
|
|
|
|||
|
|
@ -74,12 +74,31 @@ export const walkRepositoryPaths = async (
|
|||
|
||||
if (skippedLarge > 0) {
|
||||
const isDefault = maxFileSizeBytes === DEFAULT_MAX_FILE_SIZE_BYTES;
|
||||
const isOverrideUnset = !process.env.GITNEXUS_MAX_FILE_SIZE;
|
||||
const suffix = isDefault ? ', likely generated/vendored' : '';
|
||||
logger.warn(` Skipped ${skippedLarge} large files (>${maxFileSizeBytes / 1024}KB${suffix})`);
|
||||
if (isVerboseIngestionEnabled()) {
|
||||
for (const p of skippedLargePaths) {
|
||||
logger.warn(` - ${p}`);
|
||||
}
|
||||
|
||||
// Always show at least the first few paths so users can diagnose why
|
||||
// edges are missing from a specific file (issue #1659). The full list is
|
||||
// gated behind GITNEXUS_VERBOSE=1 to avoid flooding output on repos with
|
||||
// many generated/vendored blobs. Sort before slicing so the preview is
|
||||
// stable across runs (fs.stat callbacks race within each batch).
|
||||
skippedLargePaths.sort();
|
||||
const SKIPPED_PREVIEW_CAP = 5;
|
||||
const showAll = isVerboseIngestionEnabled() || skippedLargePaths.length <= SKIPPED_PREVIEW_CAP;
|
||||
const preview = showAll ? skippedLargePaths : skippedLargePaths.slice(0, SKIPPED_PREVIEW_CAP);
|
||||
for (const p of preview) {
|
||||
logger.warn(` - ${p}`);
|
||||
}
|
||||
if (!showAll) {
|
||||
const remaining = skippedLargePaths.length - SKIPPED_PREVIEW_CAP;
|
||||
logger.warn(` ...and ${remaining} more (set GITNEXUS_VERBOSE=1 to list them all)`);
|
||||
}
|
||||
// Only hint about the env var when the user has not set it at all. An
|
||||
// explicit GITNEXUS_MAX_FILE_SIZE=512 happens to resolve to the same
|
||||
// bytes as the default but the operator clearly already knows the knob.
|
||||
if (isDefault && isOverrideUnset) {
|
||||
logger.warn(` Set GITNEXUS_MAX_FILE_SIZE=<KB> to include files above the default cap.`);
|
||||
}
|
||||
}
|
||||
|
||||
|
|
|
|||
|
|
@ -1,4 +1,4 @@
|
|||
import type { Capture, CaptureMatch } from 'gitnexus-shared';
|
||||
import type { Capture, CaptureMatch, ParameterTypeClass } from 'gitnexus-shared';
|
||||
import {
|
||||
findNodeAtRange,
|
||||
nodeToCapture,
|
||||
|
|
@ -9,7 +9,11 @@ import { getCppParser, getCppScopeQuery } from './query.js';
|
|||
import { getTreeSitterBufferSize } from '../../constants.js';
|
||||
import { parseSourceSafe } from '../../../tree-sitter/safe-parse.js';
|
||||
import { splitCppInclude, splitCppUsingDecl } from './import-decomposer.js';
|
||||
import { computeCppDeclarationArity, computeCppCallArity } from './arity-metadata.js';
|
||||
import {
|
||||
classifyCppParameterType,
|
||||
computeCppDeclarationArity,
|
||||
computeCppCallArity,
|
||||
} from './arity-metadata.js';
|
||||
import { markCppAnonymousNamespaceRange, markFileLocal } from './file-local-linkage.js';
|
||||
import { markCppDependentBase } from './two-phase-lookup.js';
|
||||
import { markCppAdlSiteArgs, markCppAdlSiteNoAdl, type CppAdlArgInfo } from './adl.js';
|
||||
|
|
@ -217,6 +221,14 @@ export function emitCppScopeCaptures(
|
|||
JSON.stringify(argTypes),
|
||||
);
|
||||
}
|
||||
const argTypeClasses = inferCppCallArgTypeClasses(cNode);
|
||||
if (argTypeClasses !== undefined && argTypeClasses.length > 0) {
|
||||
grouped['@reference.parameter-type-classes'] = syntheticCapture(
|
||||
'@reference.parameter-type-classes',
|
||||
cNode,
|
||||
JSON.stringify(argTypeClasses),
|
||||
);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
|
|
@ -683,6 +695,35 @@ function inferCppCallArgTypes(node: SyntaxNode): string[] | undefined {
|
|||
return types.length > 0 ? types : undefined;
|
||||
}
|
||||
|
||||
function inferCppCallArgTypeClasses(node: SyntaxNode): ParameterTypeClass[] | undefined {
|
||||
const argList = node.childForFieldName('arguments');
|
||||
if (argList === null) return undefined;
|
||||
|
||||
const classes: ParameterTypeClass[] = [];
|
||||
for (let i = 0; i < argList.childCount; i++) {
|
||||
const child = argList.child(i);
|
||||
if (child === null) continue;
|
||||
if (child.type === ',' || child.type === '(' || child.type === ')') continue;
|
||||
const litType = inferCppLiteralType(child);
|
||||
if (litType !== '') {
|
||||
classes.push(valueTypeClass(litType));
|
||||
} else if (child.type === 'identifier') {
|
||||
classes.push(lookupDeclaredTypeClassForIdentifier(child));
|
||||
} else {
|
||||
classes.push(unknownTypeClass('unknown'));
|
||||
}
|
||||
}
|
||||
return classes.length > 0 ? classes : undefined;
|
||||
}
|
||||
|
||||
function valueTypeClass(base: string): ParameterTypeClass {
|
||||
return { base, cv: 'none', indirection: 'value', pointerDepth: 0 };
|
||||
}
|
||||
|
||||
function unknownTypeClass(base: string): ParameterTypeClass {
|
||||
return { base, cv: 'unknown', indirection: 'unknown', pointerDepth: 0 };
|
||||
}
|
||||
|
||||
/**
|
||||
* Infer the canonical type name of a C++ literal AST node.
|
||||
* Returns empty string for non-literal / unknown nodes.
|
||||
|
|
@ -750,6 +791,9 @@ function lookupDeclaredTypeForIdentifier(identNode: SyntaxNode): string {
|
|||
}
|
||||
if (scope === null) return '';
|
||||
|
||||
const paramType = lookupFunctionParameterType(scope, varName);
|
||||
if (paramType !== '') return paramType;
|
||||
|
||||
// Scan declarations in the scope for a matching variable name
|
||||
for (let i = 0; i < scope.childCount; i++) {
|
||||
const stmt = scope.child(i);
|
||||
|
|
@ -763,18 +807,118 @@ function lookupDeclaredTypeForIdentifier(identNode: SyntaxNode): string {
|
|||
// Check init_declarator children for the variable name
|
||||
const declarator = stmt.childForFieldName('declarator');
|
||||
if (declarator === null) continue;
|
||||
if (declarator.type === 'init_declarator') {
|
||||
const nameChild = declarator.childForFieldName('declarator');
|
||||
if (nameChild !== null && nameChild.text === varName) {
|
||||
return normalizeCppTypeText(typeNode.text);
|
||||
}
|
||||
} else if (declarator.text === varName) {
|
||||
const nameChild = declaredNameNode(declarator);
|
||||
if (nameChild !== null && extractDeclaratorLeafName(nameChild) === varName) {
|
||||
return normalizeCppTypeText(typeNode.text);
|
||||
}
|
||||
}
|
||||
return '';
|
||||
}
|
||||
|
||||
function lookupDeclaredTypeClassForIdentifier(identNode: SyntaxNode): ParameterTypeClass {
|
||||
const varName = identNode.text;
|
||||
let scope: SyntaxNode | null = identNode.parent;
|
||||
while (
|
||||
scope !== null &&
|
||||
scope.type !== 'compound_statement' &&
|
||||
scope.type !== 'translation_unit'
|
||||
) {
|
||||
scope = scope.parent;
|
||||
}
|
||||
if (scope === null) return unknownTypeClass('unknown');
|
||||
|
||||
const paramTypeClass = lookupFunctionParameterTypeClass(scope, varName, identNode);
|
||||
if (paramTypeClass !== undefined) return paramTypeClass;
|
||||
|
||||
for (let i = 0; i < scope.childCount; i++) {
|
||||
const stmt = scope.child(i);
|
||||
if (stmt === null || stmt.type !== 'declaration') continue;
|
||||
|
||||
const typeNode = stmt.childForFieldName('type');
|
||||
if (typeNode === null) continue;
|
||||
if (typeNode.type === 'placeholder_type_specifier') continue;
|
||||
|
||||
const declarator = stmt.childForFieldName('declarator');
|
||||
if (declarator === null) continue;
|
||||
const nameChild = declaredNameNode(declarator);
|
||||
if (nameChild === null || extractDeclaratorLeafName(nameChild) !== varName) continue;
|
||||
|
||||
const typeClass = classifyCppParameterType(
|
||||
typeNode.text,
|
||||
nameChild.text,
|
||||
stmt.text.replace(/;\s*$/, ''),
|
||||
);
|
||||
if (isKnownEnumName(identNode, typeClass.base)) {
|
||||
return { ...typeClass, base: `enum:${typeClass.base}` };
|
||||
}
|
||||
return typeClass;
|
||||
}
|
||||
return unknownTypeClass('unknown');
|
||||
}
|
||||
|
||||
function lookupFunctionParameterType(scope: SyntaxNode, varName: string): string {
|
||||
const param = findEnclosingFunctionParameter(scope, varName);
|
||||
if (param === null) return '';
|
||||
const typeNode = param.childForFieldName('type');
|
||||
if (typeNode === null) return '';
|
||||
return normalizeCppTypeText(typeNode.text);
|
||||
}
|
||||
|
||||
function lookupFunctionParameterTypeClass(
|
||||
scope: SyntaxNode,
|
||||
varName: string,
|
||||
identNode: SyntaxNode,
|
||||
): ParameterTypeClass | undefined {
|
||||
const param = findEnclosingFunctionParameter(scope, varName);
|
||||
if (param === null) return undefined;
|
||||
const typeNode = param.childForFieldName('type');
|
||||
if (typeNode === null) return undefined;
|
||||
const declarator = param.childForFieldName('declarator');
|
||||
if (declarator === null) return undefined;
|
||||
const typeClass = classifyCppParameterType(typeNode.text, declarator.text, param.text);
|
||||
if (isKnownEnumName(identNode, typeClass.base)) {
|
||||
return { ...typeClass, base: `enum:${typeClass.base}` };
|
||||
}
|
||||
return typeClass;
|
||||
}
|
||||
|
||||
function findEnclosingFunctionParameter(scope: SyntaxNode, varName: string): SyntaxNode | null {
|
||||
let node: SyntaxNode | null = scope.parent;
|
||||
while (node !== null) {
|
||||
if (node.type === 'function_definition' || node.type === 'function_declarator') {
|
||||
const fnDecl =
|
||||
node.type === 'function_declarator'
|
||||
? node
|
||||
: findFirstDescendantOfType(node, 'function_declarator');
|
||||
const params = fnDecl?.childForFieldName('parameters') ?? null;
|
||||
if (params !== null) {
|
||||
for (let i = 0; i < params.namedChildCount; i++) {
|
||||
const param = params.namedChild(i);
|
||||
if (param === null || param.type !== 'parameter_declaration') continue;
|
||||
const declarator = param.childForFieldName('declarator');
|
||||
if (declarator !== null && extractDeclaratorLeafName(declarator) === varName) {
|
||||
return param;
|
||||
}
|
||||
}
|
||||
}
|
||||
return null;
|
||||
}
|
||||
node = node.parent;
|
||||
}
|
||||
return null;
|
||||
}
|
||||
|
||||
function declaredNameNode(declarator: SyntaxNode): SyntaxNode | null {
|
||||
if (declarator.type !== 'init_declarator') return declarator;
|
||||
for (let i = 0; i < declarator.namedChildCount; i++) {
|
||||
const child = declarator.namedChild(i);
|
||||
if (child === null) continue;
|
||||
if (child.type === 'identifier') return child;
|
||||
if (child.type.endsWith('_declarator')) return child;
|
||||
}
|
||||
return declarator.childForFieldName('declarator');
|
||||
}
|
||||
|
||||
/** Normalize a type-specifier text for argument type matching.
|
||||
* Strips qualifiers (const, volatile), namespace prefixes (std::),
|
||||
* and pointer/reference markers. */
|
||||
|
|
@ -786,6 +930,25 @@ function normalizeCppTypeText(text: string): string {
|
|||
return t;
|
||||
}
|
||||
|
||||
function isKnownEnumName(node: SyntaxNode, typeName: string): boolean {
|
||||
if (typeName === '' || typeName === 'unknown') return false;
|
||||
let root: SyntaxNode = node;
|
||||
while (root.parent !== null) root = root.parent;
|
||||
const stack: SyntaxNode[] = [root];
|
||||
while (stack.length > 0) {
|
||||
const cur = stack.pop()!;
|
||||
if (cur.type === 'enum_specifier') {
|
||||
const name = cur.childForFieldName('name');
|
||||
if (name?.text === typeName) return true;
|
||||
}
|
||||
for (let i = 0; i < cur.childCount; i++) {
|
||||
const child = cur.child(i);
|
||||
if (child !== null) stack.push(child);
|
||||
}
|
||||
}
|
||||
return false;
|
||||
}
|
||||
|
||||
/**
|
||||
* Detect whether a `namespace_definition` AST node is inline.
|
||||
* Tree-sitter-cpp exposes the `inline` keyword as an anonymous child
|
||||
|
|
@ -1247,7 +1410,9 @@ function extractDeclaratorLeafName(node: SyntaxNode): string | null {
|
|||
const next =
|
||||
cur.childForFieldName('declarator') ??
|
||||
// parenthesized_declarator: single named child
|
||||
(cur.type === 'parenthesized_declarator' ? cur.namedChild(0) : null);
|
||||
(cur.type === 'parenthesized_declarator' || cur.type.endsWith('_declarator')
|
||||
? cur.namedChild(0)
|
||||
: null);
|
||||
if (next === null) return null;
|
||||
cur = next;
|
||||
}
|
||||
|
|
|
|||
|
|
@ -20,20 +20,27 @@
|
|||
* NOT: flip compatible↔incompatible; pass through unknown.
|
||||
*/
|
||||
|
||||
import type { ArityVerdict, Callsite, ConstraintContext, SymbolDefinition } from 'gitnexus-shared';
|
||||
import type {
|
||||
ArityVerdict,
|
||||
Callsite,
|
||||
ConstraintContext,
|
||||
ParameterTypeClass,
|
||||
SymbolDefinition,
|
||||
} from 'gitnexus-shared';
|
||||
import { classifyType, type TypeClass } from './type-classifier.js';
|
||||
import type { ConstraintExpr, CppConstraintPayload } from './constraint-extractor.js';
|
||||
|
||||
type AtomicEvaluator = (argClasses: readonly TypeClass[]) => ArityVerdict;
|
||||
interface ConstraintArgClass {
|
||||
readonly typeClass: TypeClass;
|
||||
readonly shape?: ParameterTypeClass;
|
||||
}
|
||||
|
||||
type AtomicEvaluator = (args: readonly ConstraintArgClass[]) => ArityVerdict;
|
||||
|
||||
/**
|
||||
* Curated Tier-A predicate registry — the four canonical
|
||||
* `<type_traits>` variable templates whose truth tables are closed-form
|
||||
* over our coarse `TypeClass` enum.
|
||||
*
|
||||
* Deferred predicates that need a cv/ref/pointer sidecar on
|
||||
* `normalizeCppParamType` (today the normalizer strips those markers
|
||||
* before storage) live in #1579 as one-line follow-up adds.
|
||||
* Curated Tier-A predicate registry. Predicates that depend on pointer,
|
||||
* reference, or cv shape consult `ConstraintContext.argumentTypeClasses`.
|
||||
* Missing or unsupported shape returns 'unknown' to preserve monotonicity.
|
||||
*/
|
||||
// ISO `<type_traits>` treats `bool`, `char`, and the signed/unsigned char
|
||||
// variants as integral types (§21.3.4 Table 48), so `is_integral_v<bool>`
|
||||
|
|
@ -46,30 +53,135 @@ function isIntegralClass(c: TypeClass | undefined): boolean {
|
|||
}
|
||||
|
||||
const REGISTRY = new Map<string, AtomicEvaluator>([
|
||||
['is_integral_v', (cls) => verdictFromBool(isIntegralClass(cls[0]), cls)],
|
||||
['is_floating_point_v', (cls) => verdictFromBool(cls[0] === 'floating', cls)],
|
||||
[
|
||||
'is_void_v',
|
||||
(args) => unaryVerdict(args, (arg) => isPlainValue(arg) && arg.typeClass === 'void'),
|
||||
],
|
||||
[
|
||||
'is_integral_v',
|
||||
(args) => unaryVerdict(args, (arg) => isPlainValue(arg) && isIntegralClass(arg.typeClass)),
|
||||
],
|
||||
[
|
||||
'is_floating_point_v',
|
||||
(args) => unaryVerdict(args, (arg) => isPlainValue(arg) && arg.typeClass === 'floating'),
|
||||
],
|
||||
[
|
||||
'is_arithmetic_v',
|
||||
(cls) => verdictFromBool(isIntegralClass(cls[0]) || cls[0] === 'floating', cls),
|
||||
(args) =>
|
||||
unaryVerdict(
|
||||
args,
|
||||
(arg) =>
|
||||
isPlainValue(arg) && (isIntegralClass(arg.typeClass) || arg.typeClass === 'floating'),
|
||||
),
|
||||
],
|
||||
[
|
||||
'is_enum_v',
|
||||
(args) => unaryVerdict(args, (arg) => isPlainValue(arg) && arg.typeClass === 'enum'),
|
||||
],
|
||||
[
|
||||
'is_class_v',
|
||||
(args) => unaryVerdict(args, (arg) => isPlainValue(arg) && arg.typeClass === 'class'),
|
||||
],
|
||||
[
|
||||
'is_pointer_v',
|
||||
(args) =>
|
||||
unaryShapeVerdict(args, (shape) => shape.indirection === 'pointer' && shape.pointerDepth > 0),
|
||||
],
|
||||
[
|
||||
'is_reference_v',
|
||||
(args) =>
|
||||
unaryShapeVerdict(
|
||||
args,
|
||||
(shape) => shape.indirection === 'lvalue-ref' || shape.indirection === 'rvalue-ref',
|
||||
),
|
||||
],
|
||||
[
|
||||
'is_const_v',
|
||||
(args) =>
|
||||
unaryShapeVerdict(args, (shape) => shape.cv === 'const' || shape.cv === 'const volatile', {
|
||||
requireTopLevelCv: true,
|
||||
}),
|
||||
],
|
||||
[
|
||||
'is_volatile_v',
|
||||
(args) =>
|
||||
unaryShapeVerdict(args, (shape) => shape.cv === 'volatile' || shape.cv === 'const volatile', {
|
||||
requireTopLevelCv: true,
|
||||
}),
|
||||
],
|
||||
// NOTE: cv-qualifiers are stripped by `normalizeCppParamType` before the
|
||||
// type token reaches `classifyType`, so `is_same_v<const T, T>` returns
|
||||
// `'compatible'` instead of the ISO-correct `false`. Tracked under the
|
||||
// cv-sidecar refactor in #1579's "Out of scope" list; until that lands
|
||||
// this approximation matches the common `is_same_v<T, ConcreteType>`
|
||||
// dispatch idiom and silently degrades on cv-distinct compares.
|
||||
[
|
||||
'is_same_v',
|
||||
(cls) => {
|
||||
if (cls.length < 2 || cls[0] === 'unknown' || cls[1] === 'unknown') return 'unknown';
|
||||
return cls[0] === cls[1] ? 'compatible' : 'incompatible';
|
||||
(args) => {
|
||||
if (args.length < 2 || args[0].typeClass === 'unknown' || args[1].typeClass === 'unknown') {
|
||||
return 'unknown';
|
||||
}
|
||||
return args[0].typeClass === args[1].typeClass ? 'compatible' : 'incompatible';
|
||||
},
|
||||
],
|
||||
]);
|
||||
|
||||
function verdictFromBool(predicate: boolean, cls: readonly TypeClass[]): ArityVerdict {
|
||||
if (cls[0] === 'unknown') return 'unknown';
|
||||
return predicate ? 'compatible' : 'incompatible';
|
||||
function unaryVerdict(
|
||||
args: readonly ConstraintArgClass[],
|
||||
predicate: (arg: ConstraintArgClass) => boolean,
|
||||
): ArityVerdict {
|
||||
const arg = args[0];
|
||||
if (arg === undefined || arg.typeClass === 'unknown') return 'unknown';
|
||||
return predicate(arg) ? 'compatible' : 'incompatible';
|
||||
}
|
||||
|
||||
function unaryShapeVerdict(
|
||||
args: readonly ConstraintArgClass[],
|
||||
predicate: (shape: ParameterTypeClass) => boolean,
|
||||
options: { readonly requireTopLevelCv?: boolean } = {},
|
||||
): ArityVerdict {
|
||||
const arg = args[0];
|
||||
if (arg === undefined || arg.typeClass === 'unknown') return 'unknown';
|
||||
const shape = arg.shape;
|
||||
if (shape === undefined || shape.indirection === 'unknown' || shape.cv === 'unknown') {
|
||||
return 'unknown';
|
||||
}
|
||||
if (options.requireTopLevelCv === true && shape.indirection === 'pointer') {
|
||||
return 'unknown';
|
||||
}
|
||||
return predicate(shape) ? 'compatible' : 'incompatible';
|
||||
}
|
||||
|
||||
function isPlainValue(arg: ConstraintArgClass): boolean {
|
||||
const shape = arg.shape;
|
||||
if (shape === undefined) return true;
|
||||
return shape.indirection === 'value';
|
||||
}
|
||||
|
||||
function classifyConstraintArg(
|
||||
token: string | undefined,
|
||||
shape?: ParameterTypeClass,
|
||||
): ConstraintArgClass {
|
||||
if (shape !== undefined && shape.base.startsWith('enum:')) {
|
||||
return { typeClass: 'enum', shape };
|
||||
}
|
||||
const typeClass = token === undefined || token === '' ? 'unknown' : classifyType(token);
|
||||
return { typeClass, ...(shape !== undefined ? { shape } : {}) };
|
||||
}
|
||||
|
||||
function tokenForArg(ctx: ConstraintContext, argIdx: number): string | undefined {
|
||||
const shape = ctx.argumentTypeClasses?.[argIdx];
|
||||
if (shape?.base.startsWith('enum:')) return shape.base;
|
||||
return ctx.argumentTypes?.[argIdx];
|
||||
}
|
||||
|
||||
function shapeForTemplateParam(
|
||||
ctx: ConstraintContext,
|
||||
paramName: string,
|
||||
argIdx: number,
|
||||
def?: SymbolDefinition,
|
||||
): ParameterTypeClass | undefined {
|
||||
const argShape = ctx.argumentTypeClasses?.[argIdx];
|
||||
if (argShape === undefined) return undefined;
|
||||
|
||||
const paramShape = def?.parameterTypeClasses?.[argIdx];
|
||||
if (paramShape === undefined) return argShape;
|
||||
if (paramShape.base === paramName && paramShape.indirection === 'value') return argShape;
|
||||
return undefined;
|
||||
}
|
||||
|
||||
/** Public surface — registered as `ScopeResolver.constraintCompatibility`. */
|
||||
|
|
@ -80,13 +192,14 @@ export function cppConstraintCompatibility(
|
|||
): ArityVerdict {
|
||||
const payload = def.templateConstraints as CppConstraintPayload | undefined;
|
||||
if (payload === undefined) return 'unknown';
|
||||
return evaluate(payload.expr, payload, ctx);
|
||||
return evaluate(payload.expr, payload, ctx, def);
|
||||
}
|
||||
|
||||
function evaluate(
|
||||
expr: ConstraintExpr,
|
||||
payload: CppConstraintPayload,
|
||||
ctx: ConstraintContext,
|
||||
def?: SymbolDefinition,
|
||||
): ArityVerdict {
|
||||
switch (expr.kind) {
|
||||
case 'unknown':
|
||||
|
|
@ -96,17 +209,18 @@ function evaluate(
|
|||
if (evaluator === undefined) return 'unknown';
|
||||
const classes = expr.args.map((paramName) => {
|
||||
const argIdx = payload.paramArgIndex[paramName];
|
||||
if (argIdx === undefined) return 'unknown' as TypeClass;
|
||||
const token = ctx.argumentTypes?.[argIdx];
|
||||
if (token === undefined || token === '') return 'unknown' as TypeClass;
|
||||
return classifyType(token);
|
||||
if (argIdx === undefined) return { typeClass: 'unknown' as TypeClass };
|
||||
return classifyConstraintArg(
|
||||
tokenForArg(ctx, argIdx),
|
||||
shapeForTemplateParam(ctx, paramName, argIdx, def),
|
||||
);
|
||||
});
|
||||
return evaluator(classes);
|
||||
}
|
||||
case 'and': {
|
||||
let result: ArityVerdict = 'compatible';
|
||||
for (const child of expr.children) {
|
||||
const v = evaluate(child, payload, ctx);
|
||||
const v = evaluate(child, payload, ctx, def);
|
||||
if (v === 'incompatible') return 'incompatible';
|
||||
if (v === 'unknown') result = 'unknown';
|
||||
}
|
||||
|
|
@ -115,14 +229,14 @@ function evaluate(
|
|||
case 'or': {
|
||||
let result: ArityVerdict = 'incompatible';
|
||||
for (const child of expr.children) {
|
||||
const v = evaluate(child, payload, ctx);
|
||||
const v = evaluate(child, payload, ctx, def);
|
||||
if (v === 'compatible') return 'compatible';
|
||||
if (v === 'unknown') result = 'unknown';
|
||||
}
|
||||
return result;
|
||||
}
|
||||
case 'not': {
|
||||
const v = evaluate(expr.child, payload, ctx);
|
||||
const v = evaluate(expr.child, payload, ctx, def);
|
||||
if (v === 'compatible') return 'incompatible';
|
||||
if (v === 'incompatible') return 'compatible';
|
||||
return 'unknown';
|
||||
|
|
|
|||
|
|
@ -1,32 +1,30 @@
|
|||
/**
|
||||
* C++ conversion-rank scoring for overload resolution (#1578).
|
||||
* C++ conversion-rank scoring for overload resolution (#1578, #1637).
|
||||
*
|
||||
* Operates on **normalized** type strings (output of
|
||||
* `normalizeCppParamType` in `arity-metadata.ts`). After normalization:
|
||||
* - int/long/short/unsigned → 'int'
|
||||
* - float/double → 'double'
|
||||
* - char → 'char', bool → 'bool'
|
||||
*
|
||||
* Because the normalizer collapses promotion pairs (int↔long,
|
||||
* float↔double) to the same string, those promotions are invisible at
|
||||
* this layer — they appear as exact matches (rank 0).
|
||||
* Operates on normalized type strings (output of `normalizeCppParamType`
|
||||
* in `arity-metadata.ts`) plus optional shape sidecars from #1630.
|
||||
* Normalization intentionally collapses cv/ref/pointer spelling for stable
|
||||
* graph IDs, so pointer/nullptr rules must consult `ParameterTypeClass`.
|
||||
*
|
||||
* Post-normalization ranking:
|
||||
* - rank 0 — exact (same normalized type)
|
||||
* - rank 1 — integral promotion (char→int, bool→int)
|
||||
* - rank 2 — standard arithmetic conversion (int↔double, char→double,
|
||||
* bool→double)
|
||||
* - Infinity — mismatch (string↔int, user types, pointers, etc.)
|
||||
* - rank 0: exact (same normalized type)
|
||||
* - rank 1: integral promotion (char -> int, bool -> int)
|
||||
* - rank 2: standard conversion (arithmetic, nullptr -> T*, T* -> bool,
|
||||
* T* -> void*)
|
||||
* - rank 3: nullptr -> bool (kept worse than nullptr -> T*)
|
||||
* - rank 4: ellipsis conversion (worst viable)
|
||||
* - Infinity: mismatch (string -> int, user types, unsupported shapes)
|
||||
*
|
||||
* This function is intentionally C++-specific (issue #1578 pitfall:
|
||||
* keep conversion-rank tables out of shared overload-narrowing). Other
|
||||
* languages may define their own `ConversionRankFn` in the future.
|
||||
* This function is intentionally C++-specific. Other languages may define
|
||||
* their own `ConversionRankFn` in the future.
|
||||
*/
|
||||
|
||||
import type { ParameterTypeClass } from 'gitnexus-shared';
|
||||
|
||||
/** Set of normalized arithmetic types that support implicit conversion. */
|
||||
const ARITHMETIC = new Set(['int', 'double', 'char', 'bool']);
|
||||
|
||||
/** Integral promotion targets: char→int and bool→int are rank 1. */
|
||||
/** Integral promotion targets: char -> int and bool -> int are rank 1. */
|
||||
const INTEGRAL_PROMOTION = new Map([
|
||||
['char', 'int'],
|
||||
['bool', 'int'],
|
||||
|
|
@ -35,13 +33,40 @@ const INTEGRAL_PROMOTION = new Map([
|
|||
/**
|
||||
* Return the conversion rank from `argType` to `paramType`.
|
||||
*
|
||||
* @returns 0 for exact match, 1 for integral promotion (char/bool→int),
|
||||
* 2 for standard arithmetic conversion, Infinity for mismatch.
|
||||
* @returns 0 for exact match, 1 for integral promotion, 2 for standard
|
||||
* conversion, 3 for nullptr -> bool, 4 for ellipsis, Infinity
|
||||
* for mismatch.
|
||||
*/
|
||||
export function cppConversionRank(argType: string, paramType: string): number {
|
||||
if (argType === paramType) return 0;
|
||||
// Integral promotions: char→int, bool→int (ISO C++ [conv.prom])
|
||||
export function cppConversionRank(
|
||||
argType: string,
|
||||
paramType: string,
|
||||
argTypeClass?: ParameterTypeClass,
|
||||
paramTypeClass?: ParameterTypeClass,
|
||||
): number {
|
||||
if (argType === paramType) {
|
||||
return exactShapeCompatible(argTypeClass, paramTypeClass) ? 0 : Infinity;
|
||||
}
|
||||
if (paramType === '...') return 4;
|
||||
if (INTEGRAL_PROMOTION.get(argType) === paramType) return 1;
|
||||
if (ARITHMETIC.has(argType) && ARITHMETIC.has(paramType)) return 2;
|
||||
if (argType === 'null' && isPointer(paramTypeClass)) return 2;
|
||||
if (argType === 'null' && paramType === 'bool') return 3;
|
||||
if (isPointer(argTypeClass) && paramType === 'bool') return 2;
|
||||
if (isPointer(argTypeClass) && isPointer(paramTypeClass) && paramType === 'void') return 2;
|
||||
return Infinity;
|
||||
}
|
||||
|
||||
function isPointer(typeClass: ParameterTypeClass | undefined): boolean {
|
||||
return typeClass?.indirection === 'pointer' && typeClass.pointerDepth > 0;
|
||||
}
|
||||
|
||||
function exactShapeCompatible(
|
||||
argTypeClass: ParameterTypeClass | undefined,
|
||||
paramTypeClass: ParameterTypeClass | undefined,
|
||||
): boolean {
|
||||
if (argTypeClass === undefined || paramTypeClass === undefined) return true;
|
||||
if (argTypeClass.indirection === 'unknown' || paramTypeClass.indirection === 'unknown') {
|
||||
return true;
|
||||
}
|
||||
return isPointer(argTypeClass) === isPointer(paramTypeClass);
|
||||
}
|
||||
|
|
|
|||
|
|
@ -7,11 +7,10 @@
|
|||
* the call-site inference in `captures.ts`) to one of the categories
|
||||
* the `<type_traits>` predicate registry uses for SFINAE filtering.
|
||||
*
|
||||
* Intentionally coarse: cv / pointer / reference qualifiers are stripped
|
||||
* upstream by `normalizeCppParamType`. Tier-A predicates
|
||||
* (`is_integral_v`, `is_floating_point_v`, `is_arithmetic_v`, `is_same_v`)
|
||||
* are insensitive to those modifiers per ISO `<type_traits>` semantics
|
||||
* ("including any cv-qualified variants").
|
||||
* `argumentTypes` remain normalized for overload narrowing, while
|
||||
* constraint predicates that need cv/ref/pointer shape read the parallel
|
||||
* `argumentTypeClasses` sidecar. Unknown shapes must stay unknown rather
|
||||
* than being guessed as incompatible.
|
||||
*/
|
||||
|
||||
export type TypeClass =
|
||||
|
|
@ -21,7 +20,11 @@ export type TypeClass =
|
|||
| 'char'
|
||||
| 'string'
|
||||
| 'null'
|
||||
| 'void'
|
||||
| 'enum'
|
||||
| 'class'
|
||||
| 'pointer'
|
||||
| 'reference'
|
||||
| 'unknown';
|
||||
|
||||
/**
|
||||
|
|
@ -29,13 +32,17 @@ export type TypeClass =
|
|||
* inference table in `captures.ts:inferCppLiteralType` plus the std::
|
||||
* normalization in `arity-metadata.ts:normalizeCppParamType`.
|
||||
*
|
||||
* Caller note: token must already be normalized (no `const`, no `&` / `*`,
|
||||
* no `std::` prefix). Tokens passed via `ConstraintContext.argumentTypes`
|
||||
* coming from `inferCppCallArgTypes` satisfy this.
|
||||
* Caller note: token should be normalized for overload matching. Enum
|
||||
* tokens produced by the C++ adapter use the internal `enum:<Name>`
|
||||
* prefix so `is_enum_v` does not have to guess that every user token is
|
||||
* class-like.
|
||||
*/
|
||||
export function classifyType(token: string): TypeClass {
|
||||
if (token.length === 0) return 'unknown';
|
||||
if (token.startsWith('enum:')) return 'enum';
|
||||
switch (token) {
|
||||
case 'void':
|
||||
return 'void';
|
||||
case 'int':
|
||||
return 'integral';
|
||||
case 'double':
|
||||
|
|
|
|||
|
|
@ -27,6 +27,7 @@ import { javaMethodConfig } from '../method-extractors/configs/jvm.js';
|
|||
import { createVariableExtractor } from '../variable-extractors/generic.js';
|
||||
import { javaVariableConfig } from '../variable-extractors/configs/jvm.js';
|
||||
import { createHeritageExtractor } from '../heritage-extractors/generic.js';
|
||||
import type { SymbolDefinition } from 'gitnexus-shared';
|
||||
import {
|
||||
emitJavaScopeCaptures,
|
||||
interpretJavaImport,
|
||||
|
|
@ -39,6 +40,48 @@ import {
|
|||
resolveJavaImportTarget,
|
||||
} from './java/index.js';
|
||||
|
||||
const orderJavaSameNameTypeCandidates = ({
|
||||
callSiteFilePath,
|
||||
candidates,
|
||||
}: {
|
||||
readonly typeName: string;
|
||||
readonly callSiteFilePath: string;
|
||||
readonly candidates: readonly SymbolDefinition[];
|
||||
}): readonly SymbolDefinition[] | null => {
|
||||
if (!callSiteFilePath.endsWith('.java')) return null;
|
||||
if (candidates.length <= 1) return null;
|
||||
const callerDir = splitDirectorySegments(callSiteFilePath);
|
||||
|
||||
const scored = candidates.map((candidate, index) => ({
|
||||
candidate,
|
||||
index,
|
||||
score: sharedPrefixLength(callerDir, splitDirectorySegments(candidate.filePath)),
|
||||
}));
|
||||
const bestScore = Math.max(...scored.map((entry) => entry.score));
|
||||
// When all candidates tie, we have no structural signal to prefer one path.
|
||||
// Returning null keeps downstream ambiguity handling conservative.
|
||||
if (scored.every((entry) => entry.score === bestScore)) return null;
|
||||
|
||||
const ordered = [...scored]
|
||||
.sort((a, b) => b.score - a.score || a.index - b.index)
|
||||
.map((entry) => entry.candidate);
|
||||
return ordered;
|
||||
};
|
||||
|
||||
const splitDirectorySegments = (filePath: string): string[] => {
|
||||
const normalized = filePath.replace(/\\/g, '/');
|
||||
// Remove empty segments from leading/trailing/multiple slashes, then drop filename.
|
||||
const segments = normalized.split('/').filter(Boolean);
|
||||
return segments.slice(0, -1);
|
||||
};
|
||||
|
||||
const sharedPrefixLength = (left: readonly string[], right: readonly string[]): number => {
|
||||
const max = Math.min(left.length, right.length);
|
||||
let idx = 0;
|
||||
while (idx < max && left[idx] === right[idx]) idx += 1;
|
||||
return idx;
|
||||
};
|
||||
|
||||
export const javaProvider = defineLanguage({
|
||||
id: SupportedLanguages.Java,
|
||||
extensions: ['.java'],
|
||||
|
|
@ -87,4 +130,5 @@ export const javaProvider = defineLanguage({
|
|||
receiverBinding: javaReceiverBinding,
|
||||
arityCompatibility: javaArityCompatibility,
|
||||
resolveImportTarget: resolveJavaImportTarget,
|
||||
orderSameNameTypeCandidates: orderJavaSameNameTypeCandidates,
|
||||
});
|
||||
|
|
|
|||
12
gitnexus/src/core/ingestion/languages/javascript/arity.ts
Normal file
12
gitnexus/src/core/ingestion/languages/javascript/arity.ts
Normal file
|
|
@ -0,0 +1,12 @@
|
|||
/**
|
||||
* Arity compatibility for JavaScript.
|
||||
*
|
||||
* Delegates to `typescriptArityCompatibility` unchanged — JavaScript
|
||||
* supports the same arity constructs (rest parameters `...args`, default
|
||||
* parameters `p = v`) and the metadata shape (`parameterCount`,
|
||||
* `requiredParameterCount`, `parameterTypes`) is synthesized by the same
|
||||
* `computeTsArityMetadata` function (which understands both TS and JS
|
||||
* parameter node types via `extractTsJsParameters`).
|
||||
*/
|
||||
|
||||
export { typescriptArityCompatibility as jsArityCompatibility } from '../typescript/arity.js';
|
||||
722
gitnexus/src/core/ingestion/languages/javascript/captures.ts
Normal file
722
gitnexus/src/core/ingestion/languages/javascript/captures.ts
Normal file
|
|
@ -0,0 +1,722 @@
|
|||
/**
|
||||
* `emitScopeCaptures` for JavaScript.
|
||||
*
|
||||
* Adapts `emitTsScopeCaptures` for the JavaScript grammar:
|
||||
*
|
||||
* 1. **JS grammar** — uses `tree-sitter-javascript` instead of
|
||||
* `tree-sitter-typescript`. The JS scope query is a subset of the
|
||||
* TypeScript one (TypeScript-only node types dropped).
|
||||
*
|
||||
* 2. **CJS `require()` decomposition** — `const { X } = require('./m')`
|
||||
* and `const X = require('./m')` are walked in a post-query pass and
|
||||
* synthesized as `@import.kind/name/alias/source` markers so that
|
||||
* `interpretJsImport` can recover a `ParsedImport` using the same
|
||||
* shape as the TypeScript ESM decomposer.
|
||||
*
|
||||
* 3. **JSDoc type bindings** — JavaScript has no static type annotations
|
||||
* so `@type-binding.parameter` / `@type-binding.return` must be
|
||||
* inferred from leading JSDoc comments. A lightweight regex scanner
|
||||
* (`parseJsDocParams` / `parseJsDocReturn`) extracts `@param {T} n`
|
||||
* and `@returns {T}` tags and emits synthetic captures positioned on
|
||||
* the annotated function node.
|
||||
*
|
||||
* 4. **Shared synthesis passes** — destructuring, for-of map-tuple, and
|
||||
* instanceof narrowing passes are duplicated from `typescript/captures.ts`
|
||||
* (they are pure AST operations with no grammar-specific logic).
|
||||
*
|
||||
* Pure given the input source text. No I/O, no globals consulted.
|
||||
*/
|
||||
|
||||
import type { Capture, CaptureMatch } from 'gitnexus-shared';
|
||||
import {
|
||||
findNodeAtRange,
|
||||
nodeToCapture,
|
||||
syntheticCapture,
|
||||
type SyntaxNode,
|
||||
} from '../../utils/ast-helpers.js';
|
||||
import { splitImportStatement } from '../typescript/import-decomposer.js';
|
||||
import { getJsParser, getJsScopeQuery, jsCachedTreeMatchesGrammar } from './query.js';
|
||||
import { computeTsArityMetadata } from '../typescript/arity-metadata.js';
|
||||
import { synthesizeTsReceiverBinding } from '../typescript/receiver-binding.js';
|
||||
import { getTreeSitterBufferSize } from '../../constants.js';
|
||||
import { parseSourceSafe } from '../../../tree-sitter/safe-parse.js';
|
||||
|
||||
/** JS function-like node types that may carry a synthesized `this` binding.
|
||||
* Kept in sync with the `@scope.function` patterns in `query.ts`. */
|
||||
const FUNCTION_NODE_TYPES = [
|
||||
'method_definition',
|
||||
'arrow_function',
|
||||
'function_expression',
|
||||
'function_declaration',
|
||||
'generator_function_declaration',
|
||||
] as const;
|
||||
|
||||
/** Declaration anchors that carry function-like arity metadata. */
|
||||
const FUNCTION_DECL_TAGS = ['@declaration.method', '@declaration.function'] as const;
|
||||
|
||||
/** Callsite anchors that should carry `@reference.arity` + param types. */
|
||||
const CALL_TAGS = [
|
||||
'@reference.call.free',
|
||||
'@reference.call.member',
|
||||
'@reference.call.constructor',
|
||||
] as const;
|
||||
|
||||
function pickFirstDefined(grouped: CaptureMatch, tags: readonly string[]): Capture | undefined {
|
||||
for (const tag of tags) {
|
||||
const cap = grouped[tag];
|
||||
if (cap !== undefined) return cap;
|
||||
}
|
||||
return undefined;
|
||||
}
|
||||
|
||||
/** Filter `@reference.read.member` in non-read contexts (same logic as TS). */
|
||||
function shouldEmitReadMember(memberNode: SyntaxNode): boolean {
|
||||
const parent = memberNode.parent;
|
||||
if (parent === null) return true;
|
||||
switch (parent.type) {
|
||||
case 'call_expression':
|
||||
return parent.childForFieldName('function')?.id !== memberNode.id;
|
||||
case 'new_expression':
|
||||
return parent.childForFieldName('constructor')?.id !== memberNode.id;
|
||||
case 'assignment_expression':
|
||||
case 'augmented_assignment_expression':
|
||||
return parent.childForFieldName('left')?.id !== memberNode.id;
|
||||
case 'jsx_self_closing_element':
|
||||
case 'jsx_opening_element':
|
||||
return parent.childForFieldName('name')?.id !== memberNode.id;
|
||||
default:
|
||||
return true;
|
||||
}
|
||||
}
|
||||
|
||||
/** Find the first JS function-like node at the given range. */
|
||||
function findFunctionNode(rootNode: SyntaxNode, range: Capture['range']): SyntaxNode | null {
|
||||
for (const nodeType of FUNCTION_NODE_TYPES) {
|
||||
const n = findNodeAtRange(rootNode, range, nodeType);
|
||||
if (n !== null) return n;
|
||||
}
|
||||
return null;
|
||||
}
|
||||
|
||||
/** Infer a callsite argument's static type from literal shapes. */
|
||||
function inferArgType(argNode: SyntaxNode): string {
|
||||
switch (argNode.type) {
|
||||
case 'number':
|
||||
return 'number';
|
||||
case 'string':
|
||||
case 'template_string':
|
||||
return 'string';
|
||||
case 'true':
|
||||
case 'false':
|
||||
return 'boolean';
|
||||
case 'null':
|
||||
return 'null';
|
||||
case 'undefined':
|
||||
return 'undefined';
|
||||
case 'array':
|
||||
return 'Array';
|
||||
case 'object':
|
||||
return 'object';
|
||||
case 'regex':
|
||||
return 'RegExp';
|
||||
case 'new_expression': {
|
||||
const ctor = argNode.childForFieldName('constructor');
|
||||
return ctor?.text ?? '';
|
||||
}
|
||||
default:
|
||||
return '';
|
||||
}
|
||||
}
|
||||
|
||||
// ─── CJS require() decomposition ─────────────────────────────────────────
|
||||
|
||||
/**
|
||||
* Walk the AST and synthesize `@import.*` captures for CJS `require()` calls:
|
||||
*
|
||||
* - `const { X, Y } = require('./m')` → one match per destructured name,
|
||||
* `@import.kind = 'named'`, `@import.name = X / Y`.
|
||||
* - `const X = require('./m')` → `@import.kind = 'namespace'`,
|
||||
* `@import.alias = X` (the whole module is bound to X).
|
||||
* - `require('./m')` as a bare expression-statement → side-effect.
|
||||
*
|
||||
* CJS named-alias form (`const { X: alias } = require('./m')`) emits
|
||||
* `@import.kind = 'named-alias'` with `@import.name = X` and
|
||||
* `@import.alias = alias`.
|
||||
*
|
||||
* The synthesized markers are identical to those produced by
|
||||
* `splitImportStatement` for ESM, so `interpretJsImport` can delegate
|
||||
* unchanged to `interpretTsImport` for all cases.
|
||||
*/
|
||||
function synthesizeCjsImports(root: SyntaxNode, out: CaptureMatch[]): void {
|
||||
const stack: SyntaxNode[] = [root];
|
||||
for (;;) {
|
||||
const node = stack.pop();
|
||||
if (node === undefined) break;
|
||||
for (const child of node.namedChildren) {
|
||||
if (child !== null) stack.push(child);
|
||||
}
|
||||
|
||||
if (node.type !== 'call_expression') continue;
|
||||
|
||||
// Require call: function must be bare identifier "require".
|
||||
const fn = node.childForFieldName('function');
|
||||
if (fn === null || fn.type !== 'identifier' || fn.text !== 'require') continue;
|
||||
|
||||
const argsNode = node.childForFieldName('arguments');
|
||||
if (argsNode === null) continue;
|
||||
|
||||
// Source must be a string literal.
|
||||
const firstArg = argsNode.namedChild(0);
|
||||
if (firstArg === null || firstArg.type !== 'string') continue;
|
||||
const rawSource = firstArg.text; // includes surrounding quotes
|
||||
const source = firstArg.namedChild(0)?.text ?? rawSource.slice(1, -1);
|
||||
|
||||
const parent = node.parent;
|
||||
|
||||
// Case 1: const { X } = require('./m') OR const X = require('./m')
|
||||
if (parent?.type === 'variable_declarator') {
|
||||
const nameNode = parent.childForFieldName('name');
|
||||
if (nameNode === null) continue;
|
||||
|
||||
if (nameNode.type === 'object_pattern') {
|
||||
// Destructured: emit one match per specifier.
|
||||
for (const field of nameNode.namedChildren) {
|
||||
if (field === null) continue;
|
||||
if (field.type === 'shorthand_property_identifier_pattern') {
|
||||
const name = field.text;
|
||||
out.push({
|
||||
'@import.statement': syntheticCapture('@import.statement', node, rawSource),
|
||||
'@import.kind': syntheticCapture('@import.kind', node, 'named'),
|
||||
'@import.name': syntheticCapture('@import.name', field, name),
|
||||
'@import.source': syntheticCapture('@import.source', firstArg, source),
|
||||
});
|
||||
} else if (field.type === 'pair_pattern') {
|
||||
const key = field.childForFieldName('key');
|
||||
const value = field.childForFieldName('value');
|
||||
if (key === null || value === null || value.type !== 'identifier') continue;
|
||||
out.push({
|
||||
'@import.statement': syntheticCapture('@import.statement', node, rawSource),
|
||||
'@import.kind': syntheticCapture('@import.kind', node, 'named-alias'),
|
||||
'@import.name': syntheticCapture('@import.name', key, key.text),
|
||||
'@import.alias': syntheticCapture('@import.alias', value, value.text),
|
||||
'@import.source': syntheticCapture('@import.source', firstArg, source),
|
||||
});
|
||||
}
|
||||
}
|
||||
} else if (nameNode.type === 'identifier') {
|
||||
// Namespace-style: const X = require('./m') → bind whole module to X.
|
||||
out.push({
|
||||
'@import.statement': syntheticCapture('@import.statement', node, rawSource),
|
||||
'@import.kind': syntheticCapture('@import.kind', node, 'namespace'),
|
||||
'@import.alias': syntheticCapture('@import.alias', nameNode, nameNode.text),
|
||||
'@import.source': syntheticCapture('@import.source', firstArg, source),
|
||||
});
|
||||
}
|
||||
continue;
|
||||
}
|
||||
|
||||
// Case 2: bare require('./m') — side-effect import.
|
||||
if (parent?.type === 'expression_statement') {
|
||||
out.push({
|
||||
'@import.statement': syntheticCapture('@import.statement', node, rawSource),
|
||||
'@import.kind': syntheticCapture('@import.kind', node, 'side-effect'),
|
||||
'@import.source': syntheticCapture('@import.source', firstArg, source),
|
||||
});
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// ─── JSDoc type binding synthesis ────────────────────────────────────────
|
||||
|
||||
interface JsDocParam {
|
||||
readonly name: string;
|
||||
readonly type: string;
|
||||
}
|
||||
|
||||
/** Extract `@param {Type} name` entries from a JSDoc comment block. */
|
||||
function parseJsDocParams(text: string): readonly JsDocParam[] {
|
||||
const results: JsDocParam[] = [];
|
||||
// Match @param {Type} name or @param {Type} [name] (optional)
|
||||
const re = /@param\s+\{([^}]+)\}\s+\[?(\w+)\]?/g;
|
||||
let m: RegExpExecArray | null;
|
||||
while ((m = re.exec(text)) !== null) {
|
||||
results.push({ type: m[1].trim(), name: m[2].trim() });
|
||||
}
|
||||
return results;
|
||||
}
|
||||
|
||||
/** Extract `@returns {Type}` or `@return {Type}` from a JSDoc comment. */
|
||||
function parseJsDocReturn(text: string): string | null {
|
||||
const m = /@returns?\s+\{([^}]+)\}/.exec(text);
|
||||
return m ? m[1].trim() : null;
|
||||
}
|
||||
|
||||
/** Extract `@type {Type}` from a JSDoc comment (variable-level annotation). */
|
||||
function parseJsDocType(text: string): string | null {
|
||||
const m = /@type\s+\{([^}]+)\}/.exec(text);
|
||||
return m ? m[1].trim() : null;
|
||||
}
|
||||
|
||||
/**
|
||||
* Walk the AST and synthesize `@type-binding.*` captures from JSDoc
|
||||
* comments immediately preceding function declarations / expressions.
|
||||
*
|
||||
* Only `/** … */` block comments are scanned. Line comments (`//`) are
|
||||
* intentionally excluded — JSDoc lives in block comments.
|
||||
*
|
||||
* Emits:
|
||||
* - `@type-binding.parameter` for each `@param {T} n` tag.
|
||||
* - `@type-binding.return` for `@returns {T}` / `@return {T}`.
|
||||
* - `@type-binding.annotation` for `@type {T}` on `let`/`const`/`var`
|
||||
* declarations — covers the common `/** @type {User} */ const u = …`
|
||||
* pattern (ECMA-262 §14.3.1/§14.3.2 variable declarations).
|
||||
*
|
||||
* The binding is anchored on the function node so `tsBindingScopeFor`
|
||||
* can hoist method return-type bindings to Module scope (matching the
|
||||
* TypeScript path where `hoistTypeBindingsToModule: true`).
|
||||
*/
|
||||
function synthesizeJsDocBindings(root: SyntaxNode, out: CaptureMatch[]): void {
|
||||
const stack: SyntaxNode[] = [root];
|
||||
for (;;) {
|
||||
const node = stack.pop();
|
||||
if (node === undefined) break;
|
||||
for (const child of node.namedChildren) {
|
||||
if (child !== null) stack.push(child);
|
||||
}
|
||||
|
||||
const isFnDecl =
|
||||
node.type === 'function_declaration' || node.type === 'generator_function_declaration';
|
||||
const isMethodDef = node.type === 'method_definition';
|
||||
// Also check lexical_declaration containing an arrow/fn-expression
|
||||
const isLexDecl = node.type === 'lexical_declaration' || node.type === 'variable_declaration';
|
||||
|
||||
if (!isFnDecl && !isMethodDef && !isLexDecl) continue;
|
||||
|
||||
// For `export function foo() { ... }`, the JSDoc comment precedes the
|
||||
// wrapping export_statement, not the inner function_declaration.
|
||||
// Walk up to the export_statement so the preceding-sibling search finds it.
|
||||
const lookupNode =
|
||||
(isFnDecl || isLexDecl) && node.parent?.type === 'export_statement' ? node.parent : node;
|
||||
|
||||
// Find the preceding sibling comment.
|
||||
let sibling = lookupNode.previousNamedSibling;
|
||||
while (sibling !== null && sibling.type === 'comment') {
|
||||
const text = sibling.text;
|
||||
if (text.startsWith('/**')) {
|
||||
// Found a JSDoc block.
|
||||
const params = parseJsDocParams(text);
|
||||
const retType = parseJsDocReturn(text);
|
||||
const varType = isLexDecl ? parseJsDocType(text) : null;
|
||||
|
||||
// Determine the anchor node (the function-like node, for hoisting).
|
||||
const anchor = node;
|
||||
|
||||
for (const p of params) {
|
||||
out.push({
|
||||
'@type-binding.name': syntheticCapture('@type-binding.name', anchor, p.name),
|
||||
'@type-binding.type': syntheticCapture('@type-binding.type', anchor, p.type),
|
||||
'@type-binding.parameter': syntheticCapture('@type-binding.parameter', anchor, '1'),
|
||||
});
|
||||
}
|
||||
|
||||
if (retType !== null) {
|
||||
// For named functions, use the function name as the binding name so
|
||||
// `hoistTypeBindingsToModule` knows which function's return type this is.
|
||||
let fnName: string | null = null;
|
||||
if (isFnDecl) {
|
||||
fnName = node.childForFieldName('name')?.text ?? null;
|
||||
} else if (isMethodDef) {
|
||||
// method_definition uses `name:` field for the method name
|
||||
const nameNode = node.childForFieldName('name');
|
||||
if (nameNode?.type === 'property_identifier') fnName = nameNode.text;
|
||||
} else if (isLexDecl) {
|
||||
const declarator = node.namedChild(0);
|
||||
const nameNode = declarator?.childForFieldName('name');
|
||||
if (nameNode?.type === 'identifier') fnName = nameNode.text;
|
||||
}
|
||||
if (fnName !== null) {
|
||||
out.push({
|
||||
'@type-binding.name': syntheticCapture('@type-binding.name', anchor, fnName),
|
||||
'@type-binding.type': syntheticCapture('@type-binding.type', anchor, retType),
|
||||
'@type-binding.return': syntheticCapture('@type-binding.return', anchor, '1'),
|
||||
});
|
||||
}
|
||||
}
|
||||
|
||||
// @type {T} on let/const/var: `/** @type {User} */ const u = getUser()`.
|
||||
// Emits annotation-strength binding (source = 'annotation') so it
|
||||
// overrides any weaker constructor/alias inference on the same name.
|
||||
if (varType !== null) {
|
||||
for (const declarator of node.namedChildren) {
|
||||
if (declarator === null || declarator.type !== 'variable_declarator') continue;
|
||||
const nameNode = declarator.childForFieldName('name');
|
||||
if (nameNode === null || nameNode.type !== 'identifier') continue;
|
||||
out.push({
|
||||
'@type-binding.name': syntheticCapture('@type-binding.name', nameNode, nameNode.text),
|
||||
'@type-binding.type': syntheticCapture('@type-binding.type', nameNode, varType),
|
||||
'@type-binding.annotation': syntheticCapture(
|
||||
'@type-binding.annotation',
|
||||
nameNode,
|
||||
'1',
|
||||
),
|
||||
});
|
||||
}
|
||||
}
|
||||
|
||||
break;
|
||||
}
|
||||
sibling = sibling.previousNamedSibling;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// ─── Destructuring / for-of / instanceof (shared with TS captures) ───────
|
||||
|
||||
function synthesizeDestructuringBindings(root: SyntaxNode, out: CaptureMatch[]): void {
|
||||
const stack: SyntaxNode[] = [root];
|
||||
for (;;) {
|
||||
const node = stack.pop();
|
||||
if (node === undefined) break;
|
||||
for (const child of node.namedChildren) {
|
||||
if (child !== null) stack.push(child);
|
||||
}
|
||||
if (node.type !== 'variable_declarator') continue;
|
||||
const nameNode = node.childForFieldName('name');
|
||||
const valueNode = node.childForFieldName('value');
|
||||
if (nameNode === null || valueNode === null) continue;
|
||||
if (nameNode.type !== 'object_pattern') continue;
|
||||
if (valueNode.type !== 'identifier') continue;
|
||||
const rhsName = valueNode.text;
|
||||
for (const fieldNode of nameNode.namedChildren) {
|
||||
if (fieldNode === null) continue;
|
||||
if (fieldNode.type === 'shorthand_property_identifier_pattern') {
|
||||
const localName = fieldNode.text;
|
||||
out.push({
|
||||
'@type-binding.name': syntheticCapture('@type-binding.name', fieldNode, localName),
|
||||
'@type-binding.type': syntheticCapture(
|
||||
'@type-binding.type',
|
||||
fieldNode,
|
||||
`${rhsName}.${localName}`,
|
||||
),
|
||||
'@type-binding.destructured': syntheticCapture(
|
||||
'@type-binding.destructured',
|
||||
fieldNode,
|
||||
fieldNode.text,
|
||||
),
|
||||
});
|
||||
} else if (fieldNode.type === 'pair_pattern') {
|
||||
const key = fieldNode.childForFieldName('key');
|
||||
const value = fieldNode.childForFieldName('value');
|
||||
if (key === null || value === null || value.type !== 'identifier') continue;
|
||||
const fieldName = key.text;
|
||||
const localName = value.text;
|
||||
out.push({
|
||||
'@type-binding.name': syntheticCapture('@type-binding.name', value, localName),
|
||||
'@type-binding.type': syntheticCapture(
|
||||
'@type-binding.type',
|
||||
fieldNode,
|
||||
`${rhsName}.${fieldName}`,
|
||||
),
|
||||
'@type-binding.destructured': syntheticCapture(
|
||||
'@type-binding.destructured',
|
||||
fieldNode,
|
||||
fieldNode.text,
|
||||
),
|
||||
});
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
function synthesizeForOfMapTupleBindings(root: SyntaxNode, out: CaptureMatch[]): void {
|
||||
const stack: SyntaxNode[] = [root];
|
||||
for (;;) {
|
||||
const node = stack.pop();
|
||||
if (node === undefined) break;
|
||||
for (const child of node.namedChildren) {
|
||||
if (child !== null) stack.push(child);
|
||||
}
|
||||
if (node.type !== 'for_in_statement') continue;
|
||||
const left = node.childForFieldName('left');
|
||||
const right = node.childForFieldName('right');
|
||||
if (left === null || right === null) continue;
|
||||
if (left.type !== 'array_pattern' || right.type !== 'identifier') continue;
|
||||
const rhs = right.text;
|
||||
let slot = 0;
|
||||
for (const child of left.namedChildren) {
|
||||
if (child === null || child.type !== 'identifier') continue;
|
||||
const localName = child.text;
|
||||
out.push({
|
||||
'@type-binding.name': syntheticCapture('@type-binding.name', child, localName),
|
||||
'@type-binding.type': syntheticCapture(
|
||||
'@type-binding.type',
|
||||
child,
|
||||
`__MAP_TUPLE_${slot}__:${rhs}`,
|
||||
),
|
||||
'@type-binding.map-tuple-entry': syntheticCapture(
|
||||
'@type-binding.map-tuple-entry',
|
||||
child,
|
||||
String(slot),
|
||||
),
|
||||
});
|
||||
slot++;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
function synthesizeInstanceofNarrowings(root: SyntaxNode, out: CaptureMatch[]): void {
|
||||
const stack: SyntaxNode[] = [root];
|
||||
for (;;) {
|
||||
const node = stack.pop();
|
||||
if (node === undefined) break;
|
||||
for (const child of node.namedChildren) {
|
||||
if (child !== null) stack.push(child);
|
||||
}
|
||||
if (node.type !== 'if_statement') continue;
|
||||
const cond = node.childForFieldName('condition');
|
||||
if (cond === null) continue;
|
||||
const inner = cond.type === 'parenthesized_expression' ? cond.namedChildren[0] : cond;
|
||||
if (inner === null || inner.type !== 'binary_expression') continue;
|
||||
const op = inner.childForFieldName('operator');
|
||||
const left = inner.childForFieldName('left');
|
||||
const right = inner.childForFieldName('right');
|
||||
if (op === null || left === null || right === null) continue;
|
||||
if (op.type !== 'instanceof') continue;
|
||||
if (left.type !== 'identifier') continue;
|
||||
if (right.type !== 'identifier') continue;
|
||||
const varName = left.text;
|
||||
const typeName = right.text;
|
||||
const cons = node.childForFieldName('consequence');
|
||||
if (cons === null) continue;
|
||||
out.push({
|
||||
'@type-binding.name': syntheticCapture('@type-binding.name', cons, varName),
|
||||
'@type-binding.type': syntheticCapture('@type-binding.type', right, typeName),
|
||||
'@type-binding.instanceof-narrow': syntheticCapture(
|
||||
'@type-binding.instanceof-narrow',
|
||||
cons,
|
||||
'1',
|
||||
),
|
||||
});
|
||||
}
|
||||
}
|
||||
|
||||
// ─── Constructor field type bindings ─────────────────────────────────────
|
||||
|
||||
/**
|
||||
* Synthesize class-scope type bindings from `this.X = new Y()` assignments
|
||||
* inside constructor method bodies. Covers the traditional ES5+ OOP pattern:
|
||||
*
|
||||
* class User {
|
||||
* constructor() {
|
||||
* /** @type {Address} *\/
|
||||
* this.address = new Address();
|
||||
* }
|
||||
* }
|
||||
*
|
||||
* The emitted `@type-binding.class-field` is hoisted to the Class scope by
|
||||
* `tsBindingScopeFor` so that compound-receiver resolution can look up
|
||||
* `User.address → Address` when resolving `user.address.save()`.
|
||||
*
|
||||
* Type source priority:
|
||||
* 1. JSDoc `@type {T}` comment immediately preceding the statement
|
||||
* 2. `new Y()` constructor inference
|
||||
*/
|
||||
function synthesizeConstructorFieldBindings(root: SyntaxNode, out: CaptureMatch[]): void {
|
||||
const stack: SyntaxNode[] = [root];
|
||||
for (;;) {
|
||||
const node = stack.pop();
|
||||
if (node === undefined) break;
|
||||
for (const child of node.namedChildren) {
|
||||
if (child !== null) stack.push(child);
|
||||
}
|
||||
// Only process constructor method definitions
|
||||
if (node.type !== 'method_definition') continue;
|
||||
const nameNode = node.childForFieldName('name');
|
||||
if (nameNode?.text !== 'constructor') continue;
|
||||
|
||||
const body = node.childForFieldName('body');
|
||||
if (body === null) continue;
|
||||
|
||||
for (const stmt of body.namedChildren) {
|
||||
if (stmt === null || stmt.type !== 'expression_statement') continue;
|
||||
const expr = stmt.namedChild(0);
|
||||
if (expr === null || expr.type !== 'assignment_expression') continue;
|
||||
|
||||
const left = expr.childForFieldName('left');
|
||||
const right = expr.childForFieldName('right');
|
||||
if (left === null || right === null) continue;
|
||||
if (left.type !== 'member_expression') continue;
|
||||
|
||||
const obj = left.childForFieldName('object');
|
||||
const prop = left.childForFieldName('property');
|
||||
if (obj === null || prop === null) continue;
|
||||
if (obj.text !== 'this' || prop.type !== 'property_identifier') continue;
|
||||
|
||||
const fieldName = prop.text;
|
||||
|
||||
// Prefer JSDoc @type annotation on the preceding sibling comment.
|
||||
let typeName: string | null = null;
|
||||
const prevSib: SyntaxNode | null = stmt.previousNamedSibling;
|
||||
if (prevSib !== null && prevSib.type === 'comment') {
|
||||
const m = /@type\s*\{([^}]+)\}/.exec(prevSib.text);
|
||||
if (m?.[1]) typeName = m[1].trim();
|
||||
}
|
||||
// Fall back to constructor inference from `new Y()`.
|
||||
if (typeName === null && right.type === 'new_expression') {
|
||||
const ctor = right.childForFieldName('constructor');
|
||||
if (ctor !== null && ctor.type === 'identifier') typeName = ctor.text;
|
||||
}
|
||||
if (typeName === null) continue;
|
||||
|
||||
out.push({
|
||||
'@type-binding.name': syntheticCapture('@type-binding.name', prop, fieldName),
|
||||
'@type-binding.type': syntheticCapture('@type-binding.type', prop, typeName),
|
||||
// Anchor: positioned inside the constructor body so tsBindingScopeFor
|
||||
// can walk up from the Function (constructor) scope to the Class scope.
|
||||
'@type-binding.class-field': syntheticCapture('@type-binding.class-field', stmt, '1'),
|
||||
});
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// ─── Main emitter ──────────────────────────────────────────────────────────
|
||||
|
||||
export function emitJsScopeCaptures(
|
||||
sourceText: string,
|
||||
filePath: string,
|
||||
cachedTree?: unknown,
|
||||
): readonly CaptureMatch[] {
|
||||
let tree = cachedTree as ReturnType<ReturnType<typeof getJsParser>['parse']> | undefined;
|
||||
if (tree !== undefined && !jsCachedTreeMatchesGrammar(tree)) {
|
||||
tree = undefined;
|
||||
}
|
||||
if (tree === undefined) {
|
||||
tree = parseSourceSafe(getJsParser(filePath), sourceText, undefined, {
|
||||
bufferSize: getTreeSitterBufferSize(sourceText),
|
||||
});
|
||||
}
|
||||
|
||||
const rawMatches = getJsScopeQuery(filePath).matches(tree.rootNode);
|
||||
const out: CaptureMatch[] = [];
|
||||
|
||||
for (const m of rawMatches) {
|
||||
const grouped: Record<string, Capture> = {};
|
||||
for (const c of m.captures) {
|
||||
const tag = '@' + c.name;
|
||||
grouped[tag] = nodeToCapture(tag, c.node);
|
||||
}
|
||||
if (Object.keys(grouped).length === 0) continue;
|
||||
|
||||
// Decompose ESM import_statement / re-export export_statement.
|
||||
if (grouped['@import.statement'] !== undefined) {
|
||||
const stmtCapture = grouped['@import.statement'];
|
||||
const stmtNode =
|
||||
findNodeAtRange(tree.rootNode, stmtCapture.range, 'import_statement') ??
|
||||
findNodeAtRange(tree.rootNode, stmtCapture.range, 'export_statement');
|
||||
if (stmtNode !== null) {
|
||||
const decomposed = splitImportStatement(stmtNode);
|
||||
for (const d of decomposed) out.push(d);
|
||||
}
|
||||
continue;
|
||||
}
|
||||
|
||||
// Decompose dynamic import() calls.
|
||||
if (grouped['@import.dynamic'] !== undefined) {
|
||||
const dynCapture = grouped['@import.dynamic'];
|
||||
const callNode = findNodeAtRange(tree.rootNode, dynCapture.range, 'call_expression');
|
||||
if (callNode !== null) {
|
||||
const decomposed = splitImportStatement(callNode);
|
||||
for (const d of decomposed) out.push(d);
|
||||
}
|
||||
continue;
|
||||
}
|
||||
|
||||
// Filter @reference.read.member false-positives.
|
||||
if (grouped['@reference.read.member'] !== undefined) {
|
||||
const anchor = grouped['@reference.read.member'];
|
||||
const memberNode = findNodeAtRange(tree.rootNode, anchor.range, 'member_expression');
|
||||
if (memberNode === null || !shouldEmitReadMember(memberNode)) {
|
||||
continue;
|
||||
}
|
||||
}
|
||||
|
||||
// Synthesize arity metadata on function-like declarations.
|
||||
const declAnchor = pickFirstDefined(grouped, FUNCTION_DECL_TAGS);
|
||||
if (declAnchor !== undefined) {
|
||||
const fnNode = findFunctionNode(tree.rootNode, declAnchor.range);
|
||||
if (fnNode !== null) {
|
||||
const arity = computeTsArityMetadata(fnNode);
|
||||
if (arity.parameterCount !== undefined) {
|
||||
grouped['@declaration.parameter-count'] = syntheticCapture(
|
||||
'@declaration.parameter-count',
|
||||
fnNode,
|
||||
String(arity.parameterCount),
|
||||
);
|
||||
}
|
||||
if (arity.requiredParameterCount !== undefined) {
|
||||
grouped['@declaration.required-parameter-count'] = syntheticCapture(
|
||||
'@declaration.required-parameter-count',
|
||||
fnNode,
|
||||
String(arity.requiredParameterCount),
|
||||
);
|
||||
}
|
||||
if (arity.parameterTypes !== undefined) {
|
||||
grouped['@declaration.parameter-types'] = syntheticCapture(
|
||||
'@declaration.parameter-types',
|
||||
fnNode,
|
||||
JSON.stringify(arity.parameterTypes),
|
||||
);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// Synthesize @reference.arity on callsites.
|
||||
const callAnchor = pickFirstDefined(grouped, CALL_TAGS);
|
||||
if (callAnchor !== undefined && grouped['@reference.arity'] === undefined) {
|
||||
const callNode =
|
||||
findNodeAtRange(tree.rootNode, callAnchor.range, 'call_expression') ??
|
||||
findNodeAtRange(tree.rootNode, callAnchor.range, 'new_expression');
|
||||
if (callNode !== null) {
|
||||
const argList = callNode.childForFieldName('arguments');
|
||||
const args: SyntaxNode[] =
|
||||
argList === null
|
||||
? []
|
||||
: argList.namedChildren.filter(
|
||||
(c): c is SyntaxNode => c !== null && c.type !== 'comment',
|
||||
);
|
||||
grouped['@reference.arity'] = syntheticCapture(
|
||||
'@reference.arity',
|
||||
callNode,
|
||||
String(args.length),
|
||||
);
|
||||
grouped['@reference.parameter-types'] = syntheticCapture(
|
||||
'@reference.parameter-types',
|
||||
callNode,
|
||||
JSON.stringify(args.map(inferArgType)),
|
||||
);
|
||||
}
|
||||
}
|
||||
|
||||
out.push(grouped);
|
||||
|
||||
// Synthesize `this` receiver type-bindings on class member functions.
|
||||
const scopeFnAnchor = grouped['@scope.function'];
|
||||
if (scopeFnAnchor !== undefined) {
|
||||
const fnNode = findFunctionNode(tree.rootNode, scopeFnAnchor.range);
|
||||
if (fnNode !== null) {
|
||||
const synth = synthesizeTsReceiverBinding(fnNode);
|
||||
if (synth !== null) out.push(synth);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// Post-query synthesis passes.
|
||||
synthesizeCjsImports(tree.rootNode, out);
|
||||
synthesizeJsDocBindings(tree.rootNode, out);
|
||||
synthesizeConstructorFieldBindings(tree.rootNode, out);
|
||||
synthesizeDestructuringBindings(tree.rootNode, out);
|
||||
synthesizeForOfMapTupleBindings(tree.rootNode, out);
|
||||
synthesizeInstanceofNarrowings(tree.rootNode, out);
|
||||
|
||||
return out;
|
||||
}
|
||||
|
|
@ -0,0 +1,72 @@
|
|||
/**
|
||||
* Import-target resolver for JavaScript.
|
||||
*
|
||||
* Delegates to the TypeScript `resolveTsTarget` standard-strategy resolver
|
||||
* with `language: SupportedLanguages.JavaScript` so the resolver tries
|
||||
* `.js` / `.jsx` extensions in addition to (or instead of) `.ts` / `.tsx`.
|
||||
*
|
||||
* The `TsResolveContext.language` flag already exists in `import-target.ts`
|
||||
* and the resolver (`resolveImportPath`) already branches on it — this
|
||||
* adapter just wires the right value in.
|
||||
*
|
||||
* CJS `require()` calls reference the same module-path strings as ESM
|
||||
* `import` statements, so the resolver handles them uniformly without any
|
||||
* CJS-specific logic here.
|
||||
*
|
||||
* No `tsconfig.json` path-alias support (JavaScript projects don't use
|
||||
* `tsconfig.json` compilerOptions.paths in general). Projects that DO use
|
||||
* tsconfig-based aliases alongside JavaScript can still resolve via the
|
||||
* standard extension-suffix fallback; the alias branch is a no-op when
|
||||
* `tsconfigPaths` is null.
|
||||
*/
|
||||
|
||||
import { SupportedLanguages } from 'gitnexus-shared';
|
||||
import { resolveTsTarget, type TsResolveContext } from '../typescript/import-target.js';
|
||||
|
||||
export type JsResolveContext = TsResolveContext;
|
||||
|
||||
type PassCache = {
|
||||
readonly key: ReadonlySet<string>;
|
||||
readonly allFilePaths: Set<string>;
|
||||
readonly allFileList: readonly string[];
|
||||
readonly normalizedFileList: readonly string[];
|
||||
readonly resolveCache: Map<string, string | null>;
|
||||
};
|
||||
|
||||
/**
|
||||
* Build a memoized `resolveImportTarget` adapter for JavaScript.
|
||||
* Caches the derived arrays and per-pass resolve cache across
|
||||
* `resolveImportTarget` calls within a single workspace pass.
|
||||
*/
|
||||
export function makeJsResolveImportTarget(): (
|
||||
targetRaw: string,
|
||||
fromFile: string,
|
||||
allFilePaths: ReadonlySet<string>,
|
||||
resolutionConfig?: unknown,
|
||||
) => string | readonly string[] | null {
|
||||
let cached: PassCache | null = null;
|
||||
|
||||
return (targetRaw, fromFile, allFilePaths) => {
|
||||
if (cached === null || cached.key !== allFilePaths) {
|
||||
const allFileList = Array.from(allFilePaths);
|
||||
cached = {
|
||||
key: allFilePaths,
|
||||
allFilePaths: new Set(allFilePaths),
|
||||
allFileList,
|
||||
normalizedFileList: allFileList.map((f) => f.toLowerCase()),
|
||||
resolveCache: new Map(),
|
||||
};
|
||||
}
|
||||
|
||||
const ws: JsResolveContext = {
|
||||
fromFile,
|
||||
language: SupportedLanguages.JavaScript,
|
||||
allFilePaths: cached.allFilePaths,
|
||||
allFileList: cached.allFileList,
|
||||
normalizedFileList: cached.normalizedFileList,
|
||||
resolveCache: cached.resolveCache,
|
||||
tsconfigPaths: null,
|
||||
};
|
||||
return resolveTsTarget(targetRaw, ws);
|
||||
};
|
||||
}
|
||||
49
gitnexus/src/core/ingestion/languages/javascript/index.ts
Normal file
49
gitnexus/src/core/ingestion/languages/javascript/index.ts
Normal file
|
|
@ -0,0 +1,49 @@
|
|||
/**
|
||||
* JavaScript scope-resolution hooks (RFC #909 Ring 3, issue #928).
|
||||
*
|
||||
* Public API barrel. Consumers should import from this file rather
|
||||
* than the individual modules.
|
||||
*
|
||||
* Module layout (each file is a single concern):
|
||||
*
|
||||
* - `query.ts` — JS scope query string + lazy parser/query
|
||||
* singletons (`getJsParser`, `getJsScopeQuery`)
|
||||
* - `captures.ts` — `emitJsScopeCaptures` — runs the JS scope query,
|
||||
* synthesizes CJS require() imports and JSDoc-
|
||||
* derived type bindings, delegates arity synthesis
|
||||
* and destructuring/instanceof passes to shared
|
||||
* or TypeScript utilities
|
||||
* - `interpret.ts` — `interpretJsImport` / `interpretJsTypeBinding`
|
||||
* (delegate to TypeScript interpreters — same
|
||||
* capture-marker vocabulary)
|
||||
* - `simple-hooks.ts` — `jsBindingScopeFor` (var hoisting),
|
||||
* `jsImportOwningScope`, `jsReceiverBinding`
|
||||
* (all delegate to TypeScript counterparts)
|
||||
* - `merge-bindings.ts` — `jsMergeBindings` (LEGB via typescriptMergeBindings)
|
||||
* - `arity.ts` — `jsArityCompatibility` (delegates to TS function)
|
||||
* - `import-target.ts` — `makeJsResolveImportTarget` (memoized adapter)
|
||||
* - `scope-resolver.ts` — `javascriptScopeResolver` wiring object
|
||||
*
|
||||
* ## Known limitations
|
||||
*
|
||||
* 1. **JSDoc coverage** — `@param {T} name`, `@returns {T}` / `@return {T}`,
|
||||
* and `@type {T}` on variable declarations are synthesized. `@typedef`
|
||||
* is not yet synthesized (tracked in #1646).
|
||||
* 2. **CJS chained destructuring** — `const { X: { Y } } = require(...)`
|
||||
* (nested destructuring) emits only the outer `X` binding; `Y` is not
|
||||
* resolved.
|
||||
* 3. **Dynamic require** — `require(computedPath)` is skipped (non-literal
|
||||
* argument — cannot statically resolve the target).
|
||||
* 4. **`module.exports` / `exports.X`** — CJS export forms are not yet
|
||||
* modeled as re-exports. The finalize algorithm treats the exporting
|
||||
* module as a namespace; importers that do `const X = require('./m')`
|
||||
* bind the module namespace, and member-call resolution walks the
|
||||
* class graph from there.
|
||||
*/
|
||||
|
||||
export { emitJsScopeCaptures } from './captures.js';
|
||||
export { interpretJsImport, interpretJsTypeBinding } from './interpret.js';
|
||||
export { jsMergeBindings } from './merge-bindings.js';
|
||||
export { jsArityCompatibility } from './arity.js';
|
||||
export { makeJsResolveImportTarget } from './import-target.js';
|
||||
export { jsBindingScopeFor, jsImportOwningScope, jsReceiverBinding } from './simple-hooks.js';
|
||||
|
|
@ -0,0 +1,45 @@
|
|||
/**
|
||||
* Capture-match → semantic-shape interpreters for JavaScript.
|
||||
*
|
||||
* `interpretJsImport` delegates to `interpretTsImport` for all cases
|
||||
* because `emitJsScopeCaptures` synthesizes the same
|
||||
* `@import.kind/name/alias/source` markers for both ESM and CJS imports.
|
||||
*
|
||||
* The `@import.kind` values emitted for CJS by `captures.ts`:
|
||||
*
|
||||
* - `'named'` : `const { X } = require('./m')` → named import
|
||||
* - `'named-alias'` : `const { X: Y } = require('./m')` → aliased import
|
||||
* - `'namespace'` : `const X = require('./m')` → namespace import
|
||||
* - `'side-effect'` : `require('./m')` bare expression → side-effect
|
||||
*
|
||||
* These match the kinds `interpretTsImport` already handles for ESM
|
||||
* (`import { X }`, `import { X as Y }`, `import * as X`, `import './m'`),
|
||||
* so no new branch is needed here.
|
||||
*
|
||||
* `interpretJsTypeBinding` handles the JS-only `@type-binding.class-field`
|
||||
* tag before delegating to `interpretTsTypeBinding`. The class-field tag
|
||||
* is emitted by `synthesizeConstructorFieldBindings` and should produce
|
||||
* `source = 'annotation'` — the same strength as an explicit type
|
||||
* annotation. Remapping it to `@type-binding.annotation` achieves this
|
||||
* without adding a JS-specific branch to the shared TS interpreter
|
||||
* (DoD.md §2.2).
|
||||
*/
|
||||
|
||||
import type { CaptureMatch, ParsedImport, ParsedTypeBinding } from 'gitnexus-shared';
|
||||
import { interpretTsImport, interpretTsTypeBinding } from '../typescript/interpret.js';
|
||||
|
||||
export function interpretJsImport(captures: CaptureMatch): ParsedImport | null {
|
||||
return interpretTsImport(captures);
|
||||
}
|
||||
|
||||
export function interpretJsTypeBinding(captures: CaptureMatch): ParsedTypeBinding | null {
|
||||
// @type-binding.class-field is a JS-only tag emitted by
|
||||
// synthesizeConstructorFieldBindings. Remap it to the standard
|
||||
// @type-binding.annotation tag so interpretTsTypeBinding assigns
|
||||
// source = 'annotation' without a JS-specific branch in shared code.
|
||||
if (captures['@type-binding.class-field'] !== undefined) {
|
||||
const { '@type-binding.class-field': classField, ...rest } = captures;
|
||||
return interpretTsTypeBinding({ ...rest, '@type-binding.annotation': classField });
|
||||
}
|
||||
return interpretTsTypeBinding(captures);
|
||||
}
|
||||
|
|
@ -0,0 +1,21 @@
|
|||
/**
|
||||
* Binding-merge precedence for JavaScript.
|
||||
*
|
||||
* JavaScript has no TypeScript declaration-merging (no `interface + class`
|
||||
* coexisting in the same scope, no `namespace + class` dual-space declarations).
|
||||
* However, `typescriptMergeBindings` handles these by falling back to
|
||||
* `['value']` for any `NodeLabel` not explicitly mapped to multiple spaces —
|
||||
* which is what every JavaScript declaration produces. The result is pure
|
||||
* LEGB precedence without any cross-space logic, which is exactly what
|
||||
* JavaScript needs.
|
||||
*
|
||||
* Reuse rather than reimplementing to keep the single source of truth for
|
||||
* the tier (local 0 / import-namespace-reexport 1 / wildcard 2) ordering.
|
||||
*/
|
||||
|
||||
import type { BindingRef } from 'gitnexus-shared';
|
||||
import { typescriptMergeBindings } from '../typescript/merge-bindings.js';
|
||||
|
||||
export function jsMergeBindings(bindings: readonly BindingRef[]): readonly BindingRef[] {
|
||||
return typescriptMergeBindings(bindings);
|
||||
}
|
||||
421
gitnexus/src/core/ingestion/languages/javascript/query.ts
Normal file
421
gitnexus/src/core/ingestion/languages/javascript/query.ts
Normal file
|
|
@ -0,0 +1,421 @@
|
|||
/**
|
||||
* Tree-sitter query for JavaScript scope captures (RFC §5.1, Ring 3).
|
||||
*
|
||||
* Subset of the TypeScript scope query (`languages/typescript/query.ts`)
|
||||
* compiled against `tree-sitter-javascript`. TypeScript-only node types
|
||||
* (`interface_declaration`, `type_alias_declaration`, `enum_declaration`,
|
||||
* `internal_module`, `abstract_class_declaration`, `function_signature`,
|
||||
* `method_signature`, `abstract_method_signature`, `type_annotation`,
|
||||
* `public_field_definition`) are dropped because:
|
||||
*
|
||||
* 1. The JS grammar doesn't define them — the query compiler would
|
||||
* throw `InvalidNodeType` if they were included.
|
||||
* 2. JavaScript has no static type annotations, so the `@type-binding.*`
|
||||
* patterns derived from TS annotation nodes don't apply.
|
||||
*
|
||||
* What IS shared with the TypeScript query:
|
||||
*
|
||||
* - Scope patterns: `program`, `class_declaration`, `(class)` (the JS
|
||||
* grammar node for class expressions — NOT `class_expression`, which
|
||||
* does not exist in `tree-sitter-javascript`), `function_declaration`,
|
||||
* `generator_function_declaration`, `function_expression`,
|
||||
* `arrow_function`, `method_definition`.
|
||||
* - Declaration patterns for functions, classes, const/let/var,
|
||||
* object-property arrows (Zustand, TanStack, etc.), and HOC-wrapped
|
||||
* variable declarations (forwardRef / memo / useCallback / useMemo).
|
||||
* - Import patterns: `import_statement`, `export_statement` re-exports,
|
||||
* and dynamic `import()` (represented as `call_expression(import)` in
|
||||
* both grammars — the `import` leaf node exists in tree-sitter-javascript
|
||||
* as well as tree-sitter-typescript).
|
||||
* - Type-binding patterns that work without static annotations:
|
||||
* constructor inference (`new User()`), call-result alias
|
||||
* (`const u = getUser()`), member-access alias (`const a = u.addr`),
|
||||
* identifier alias, assignment rebind, and for-of element bindings.
|
||||
* JSDoc-derived type bindings (`@param {User} u`, `@returns {User}`)
|
||||
* are handled separately in `captures.ts` via comment-node scanning.
|
||||
* - Reference patterns: free calls, member calls, constructor calls,
|
||||
* write-access, read-access, and dynamic import.
|
||||
*
|
||||
* CJS `require()` is NOT captured here; it is handled in `captures.ts`
|
||||
* by scanning parent context (destructured vs. namespace) of `call_expression`
|
||||
* nodes whose callee is the identifier `require`.
|
||||
*
|
||||
* Grammar version: `tree-sitter-javascript` pinned in gitnexus/package.json.
|
||||
*
|
||||
* Exposes lazy `Parser` and `Query` singletons so callers don't pay
|
||||
* tree-sitter init cost per file.
|
||||
*/
|
||||
|
||||
import Parser from 'tree-sitter';
|
||||
import JS from 'tree-sitter-javascript';
|
||||
|
||||
const JS_GRAMMAR = JS as Parameters<Parser['setLanguage']>[0];
|
||||
|
||||
/** True when the file should be parsed with the JSX-extended query. */
|
||||
function isJsxFile(filePath: string): boolean {
|
||||
return filePath.endsWith('.jsx');
|
||||
}
|
||||
|
||||
const JAVASCRIPT_SCOPE_QUERY = `
|
||||
;; Scopes — module / class-likes / function-likes
|
||||
(program) @scope.module
|
||||
|
||||
(class_declaration) @scope.class
|
||||
(class) @scope.class
|
||||
|
||||
(function_declaration) @scope.function
|
||||
(generator_function_declaration) @scope.function
|
||||
(function_expression) @scope.function
|
||||
(arrow_function) @scope.function
|
||||
(method_definition) @scope.function
|
||||
|
||||
;; Declarations — classes
|
||||
(class_declaration
|
||||
name: (identifier) @declaration.name) @declaration.class
|
||||
|
||||
;; Declarations — methods (inside class bodies)
|
||||
(method_definition
|
||||
name: (property_identifier) @declaration.name) @declaration.method
|
||||
|
||||
;; Declarations — class fields (JS uses field_definition, not public_field_definition)
|
||||
(field_definition
|
||||
property: (property_identifier) @declaration.name) @declaration.property
|
||||
|
||||
;; Declarations — free functions
|
||||
(function_declaration
|
||||
name: (identifier) @declaration.name) @declaration.function
|
||||
|
||||
(generator_function_declaration
|
||||
name: (identifier) @declaration.name) @declaration.function
|
||||
|
||||
;; Arrow / function-expression assigned to a const/let/var.
|
||||
;; Anchor discipline: @declaration.function sits on the INNER arrow or
|
||||
;; function_expression, NOT on the lexical_declaration wrapper. This
|
||||
;; aligns anchor.range with the @scope.function range so
|
||||
;; pass2AttachDeclarations resolves the innermost scope correctly and
|
||||
;; resolveCallerGraphId walks up to the right caller anchor.
|
||||
(lexical_declaration
|
||||
(variable_declarator
|
||||
name: (identifier) @declaration.name
|
||||
value: (arrow_function) @declaration.function))
|
||||
|
||||
(lexical_declaration
|
||||
(variable_declarator
|
||||
name: (identifier) @declaration.name
|
||||
value: (function_expression) @declaration.function))
|
||||
|
||||
(export_statement
|
||||
declaration: (lexical_declaration
|
||||
(variable_declarator
|
||||
name: (identifier) @declaration.name
|
||||
value: (arrow_function) @declaration.function)))
|
||||
|
||||
(export_statement
|
||||
declaration: (lexical_declaration
|
||||
(variable_declarator
|
||||
name: (identifier) @declaration.name
|
||||
value: (function_expression) @declaration.function)))
|
||||
|
||||
(variable_declaration
|
||||
(variable_declarator
|
||||
name: (identifier) @declaration.name
|
||||
value: (arrow_function) @declaration.function))
|
||||
|
||||
(variable_declaration
|
||||
(variable_declarator
|
||||
name: (identifier) @declaration.name
|
||||
value: (function_expression) @declaration.function))
|
||||
|
||||
;; Object-property arrows / function expressions named by their pair key.
|
||||
;; Same anchor discipline as the lexical_declaration block above: the
|
||||
;; @declaration.function capture must sit on the INNER arrow/fn-expression.
|
||||
(pair
|
||||
key: (property_identifier) @declaration.name
|
||||
value: (arrow_function) @declaration.function)
|
||||
|
||||
(pair
|
||||
key: (property_identifier) @declaration.name
|
||||
value: (function_expression) @declaration.function)
|
||||
|
||||
(pair
|
||||
key: (string (string_fragment) @declaration.name)
|
||||
value: (arrow_function) @declaration.function)
|
||||
|
||||
(pair
|
||||
key: (string (string_fragment) @declaration.name)
|
||||
value: (function_expression) @declaration.function)
|
||||
|
||||
;; HOC-wrapped variable declarations: const X = HOC((args) => { ... }).
|
||||
;; Covers React.forwardRef, memo, useCallback, useMemo, observer,
|
||||
;; debounce, and any user-defined HOC factory.
|
||||
(lexical_declaration
|
||||
(variable_declarator
|
||||
name: (identifier) @declaration.name
|
||||
value: (call_expression
|
||||
arguments: (arguments
|
||||
(arrow_function) @declaration.function))))
|
||||
|
||||
(lexical_declaration
|
||||
(variable_declarator
|
||||
name: (identifier) @declaration.name
|
||||
value: (call_expression
|
||||
arguments: (arguments
|
||||
(function_expression) @declaration.function))))
|
||||
|
||||
(export_statement
|
||||
declaration: (lexical_declaration
|
||||
(variable_declarator
|
||||
name: (identifier) @declaration.name
|
||||
value: (call_expression
|
||||
arguments: (arguments
|
||||
(arrow_function) @declaration.function)))))
|
||||
|
||||
(export_statement
|
||||
declaration: (lexical_declaration
|
||||
(variable_declarator
|
||||
name: (identifier) @declaration.name
|
||||
value: (call_expression
|
||||
arguments: (arguments
|
||||
(function_expression) @declaration.function)))))
|
||||
|
||||
(variable_declaration
|
||||
(variable_declarator
|
||||
name: (identifier) @declaration.name
|
||||
value: (call_expression
|
||||
arguments: (arguments
|
||||
(arrow_function) @declaration.function))))
|
||||
|
||||
(variable_declaration
|
||||
(variable_declarator
|
||||
name: (identifier) @declaration.name
|
||||
value: (call_expression
|
||||
arguments: (arguments
|
||||
(function_expression) @declaration.function))))
|
||||
|
||||
;; Variable / constant declarations (non-function values).
|
||||
(lexical_declaration
|
||||
(variable_declarator
|
||||
name: (identifier) @declaration.name)) @declaration.const
|
||||
|
||||
(export_statement
|
||||
declaration: (lexical_declaration
|
||||
(variable_declarator
|
||||
name: (identifier) @declaration.name))) @declaration.const
|
||||
|
||||
(variable_declaration
|
||||
(variable_declarator
|
||||
name: (identifier) @declaration.name)) @declaration.variable
|
||||
|
||||
;; Imports (ESM) — single anchor per statement; decomposer emits per-specifier markers.
|
||||
(import_statement) @import.statement
|
||||
|
||||
;; Re-exports with a source clause.
|
||||
(export_statement
|
||||
source: (string)) @import.statement
|
||||
|
||||
;; Dynamic imports: import('./m') — tree-sitter-javascript represents this
|
||||
;; as call_expression with a named import leaf as the function field,
|
||||
;; identical to tree-sitter-typescript.
|
||||
(call_expression
|
||||
function: (import)) @import.dynamic
|
||||
|
||||
;; ── Type bindings (no static annotations in JS; inferred from AST shape) ──
|
||||
|
||||
;; Constructor-inferred: const u = new User()
|
||||
(variable_declarator
|
||||
name: (identifier) @type-binding.name
|
||||
value: (new_expression
|
||||
constructor: (identifier) @type-binding.type)) @type-binding.constructor
|
||||
|
||||
;; Qualified constructor: const u = new models.User()
|
||||
(variable_declarator
|
||||
name: (identifier) @type-binding.name
|
||||
value: (new_expression
|
||||
constructor: (member_expression) @type-binding.type)) @type-binding.constructor
|
||||
|
||||
;; Call-result alias: const u = getUser()
|
||||
(variable_declarator
|
||||
name: (identifier) @type-binding.name
|
||||
value: (call_expression
|
||||
function: (identifier) @type-binding.type)) @type-binding.alias
|
||||
|
||||
;; Member-call alias: const u = svc.getUser()
|
||||
(variable_declarator
|
||||
name: (identifier) @type-binding.name
|
||||
value: (call_expression
|
||||
function: (member_expression) @type-binding.type)) @type-binding.alias
|
||||
|
||||
;; Await chain: const u = await getUser() / await svc.getUser()
|
||||
(variable_declarator
|
||||
name: (identifier) @type-binding.name
|
||||
value: (await_expression
|
||||
(call_expression
|
||||
function: (identifier) @type-binding.type))) @type-binding.alias
|
||||
|
||||
(variable_declarator
|
||||
name: (identifier) @type-binding.name
|
||||
value: (await_expression
|
||||
(call_expression
|
||||
function: (member_expression) @type-binding.type))) @type-binding.alias
|
||||
|
||||
;; Member-access alias: const addr = user.address
|
||||
(variable_declarator
|
||||
name: (identifier) @type-binding.name
|
||||
value: (member_expression) @type-binding.type) @type-binding.member-alias
|
||||
|
||||
;; Identifier alias: const alias = user
|
||||
(variable_declarator
|
||||
name: (identifier) @type-binding.name
|
||||
value: (identifier) @type-binding.type) @type-binding.alias
|
||||
|
||||
;; Assignment rebind: u = new User() / u = getUser()
|
||||
(assignment_expression
|
||||
left: (identifier) @type-binding.name
|
||||
right: (new_expression
|
||||
constructor: (identifier) @type-binding.type)) @type-binding.constructor
|
||||
|
||||
(assignment_expression
|
||||
left: (identifier) @type-binding.name
|
||||
right: (call_expression
|
||||
function: (identifier) @type-binding.type)) @type-binding.alias
|
||||
|
||||
(assignment_expression
|
||||
left: (identifier) @type-binding.name
|
||||
right: (identifier) @type-binding.type) @type-binding.alias
|
||||
|
||||
;; For-of element: for (const u of users) / for (const u of getUsers())
|
||||
(for_in_statement
|
||||
left: (identifier) @type-binding.name
|
||||
right: (identifier) @type-binding.type) @type-binding.alias
|
||||
|
||||
(for_in_statement
|
||||
left: (identifier) @type-binding.name
|
||||
right: (call_expression
|
||||
function: (identifier) @type-binding.type)) @type-binding.alias
|
||||
|
||||
(for_in_statement
|
||||
left: (identifier) @type-binding.name
|
||||
right: (call_expression
|
||||
function: (member_expression) @type-binding.type)) @type-binding.alias
|
||||
|
||||
(for_in_statement
|
||||
left: (identifier) @type-binding.name
|
||||
right: (member_expression
|
||||
property: (property_identifier) @type-binding.type)) @type-binding.alias
|
||||
|
||||
;; ── References ────────────────────────────────────────────────────────────
|
||||
|
||||
;; Free calls: fn(args). The dynamic-import filter runs in captures.ts.
|
||||
(call_expression
|
||||
function: (identifier) @reference.name) @reference.call.free
|
||||
|
||||
;; Awaited free call: await fn<T>(...) re-associated by tree-sitter.
|
||||
(call_expression
|
||||
function: (await_expression
|
||||
(identifier) @reference.name)) @reference.call.free
|
||||
|
||||
;; Member calls: obj.method() (includes optional chain).
|
||||
(call_expression
|
||||
function: (member_expression
|
||||
object: (_) @reference.receiver
|
||||
property: (property_identifier) @reference.name)) @reference.call.member
|
||||
|
||||
;; Awaited member call: await svc.m<T>(...)
|
||||
(call_expression
|
||||
function: (await_expression
|
||||
(member_expression
|
||||
object: (_) @reference.receiver
|
||||
property: (property_identifier) @reference.name))) @reference.call.member
|
||||
|
||||
;; Constructor calls: new User() / new ns.User()
|
||||
(new_expression
|
||||
constructor: (identifier) @reference.name) @reference.call.constructor
|
||||
|
||||
(new_expression
|
||||
constructor: (member_expression) @reference.call.constructor.qualified) @reference.call.constructor
|
||||
|
||||
;; Write access: obj.field = value
|
||||
(assignment_expression
|
||||
left: (member_expression
|
||||
object: (_) @reference.receiver
|
||||
property: (property_identifier) @reference.name)) @reference.write.member
|
||||
|
||||
(augmented_assignment_expression
|
||||
left: (member_expression
|
||||
object: (_) @reference.receiver
|
||||
property: (property_identifier) @reference.name)) @reference.write.member
|
||||
|
||||
;; Read access: obj.field (in read context; captures.ts filters non-reads).
|
||||
(member_expression
|
||||
object: (_) @reference.receiver
|
||||
property: (property_identifier) @reference.name) @reference.read.member
|
||||
`;
|
||||
|
||||
/** JSX-only suffix — appended when compiling against the JSX grammar for .jsx files. */
|
||||
const JSX_QUERY_SUFFIX = `
|
||||
;; <Foo />
|
||||
((jsx_self_closing_element
|
||||
name: (identifier) @reference.name) @reference.call.free
|
||||
(#match? @reference.name "^[A-Z]"))
|
||||
|
||||
;; <Foo> ... </Foo>
|
||||
((jsx_opening_element
|
||||
name: (identifier) @reference.name) @reference.call.free
|
||||
(#match? @reference.name "^[A-Z]"))
|
||||
|
||||
;; <Foo.Bar />
|
||||
(jsx_self_closing_element
|
||||
name: (member_expression
|
||||
object: (_) @reference.receiver
|
||||
property: (property_identifier) @reference.name)) @reference.call.member
|
||||
|
||||
(jsx_opening_element
|
||||
name: (member_expression
|
||||
object: (_) @reference.receiver
|
||||
property: (property_identifier) @reference.name)) @reference.call.member
|
||||
`;
|
||||
|
||||
let _jsParser: Parser | null = null;
|
||||
let _jsQuery: Parser.Query | null = null;
|
||||
let _jsxParser: Parser | null = null;
|
||||
let _jsxQuery: Parser.Query | null = null;
|
||||
|
||||
export function getJsParser(filePath?: string): Parser {
|
||||
// JSX files use the same JavaScript grammar in tree-sitter-javascript;
|
||||
// both .js and .jsx parse with the same grammar object. We keep separate
|
||||
// singletons only to mirror the TypeScript pattern and in case a future
|
||||
// version of the grammar diverges.
|
||||
if (filePath !== undefined && isJsxFile(filePath)) {
|
||||
if (_jsxParser === null) {
|
||||
_jsxParser = new Parser();
|
||||
_jsxParser.setLanguage(JS_GRAMMAR);
|
||||
}
|
||||
return _jsxParser;
|
||||
}
|
||||
if (_jsParser === null) {
|
||||
_jsParser = new Parser();
|
||||
_jsParser.setLanguage(JS_GRAMMAR);
|
||||
}
|
||||
return _jsParser;
|
||||
}
|
||||
|
||||
export function getJsScopeQuery(filePath?: string): Parser.Query {
|
||||
if (filePath !== undefined && isJsxFile(filePath)) {
|
||||
if (_jsxQuery === null) {
|
||||
_jsxQuery = new Parser.Query(JS_GRAMMAR, JAVASCRIPT_SCOPE_QUERY + JSX_QUERY_SUFFIX);
|
||||
}
|
||||
return _jsxQuery;
|
||||
}
|
||||
if (_jsQuery === null) {
|
||||
_jsQuery = new Parser.Query(JS_GRAMMAR, JAVASCRIPT_SCOPE_QUERY);
|
||||
}
|
||||
return _jsQuery;
|
||||
}
|
||||
|
||||
/** Validate that a cached Tree was produced by the JS grammar. */
|
||||
export function jsCachedTreeMatchesGrammar(tree: unknown): boolean {
|
||||
// eslint-disable-next-line @typescript-eslint/no-explicit-any
|
||||
const lang = (tree as any)?.getLanguage?.();
|
||||
if (lang === undefined || lang === null) return true;
|
||||
return lang === JS_GRAMMAR;
|
||||
}
|
||||
|
|
@ -0,0 +1,89 @@
|
|||
/**
|
||||
* JavaScript `ScopeResolver` registered in `SCOPE_RESOLVERS` and
|
||||
* consumed by the generic `runScopeResolution` orchestrator
|
||||
* (RFC #909 Ring 3, issue #928).
|
||||
*
|
||||
* Follows the same minimal wiring-only pattern as TypeScript (the third
|
||||
* migration). Per-hook logic lives in sibling modules:
|
||||
*
|
||||
* - `query.ts` — JS scope query + parser/query singletons
|
||||
* - `captures.ts` — `emitJsScopeCaptures` (JS grammar, CJS, JSDoc)
|
||||
* - `interpret.ts` — `interpretJsImport` (delegates to TS interpreter)
|
||||
* - `simple-hooks.ts` — `jsBindingScopeFor`, `jsImportOwningScope`,
|
||||
* `jsReceiverBinding` (all delegate to TS hooks)
|
||||
* - `merge-bindings.ts` — `jsMergeBindings` (delegates to TS function)
|
||||
* - `arity.ts` — `jsArityCompatibility` (delegates to TS function)
|
||||
* - `import-target.ts` — `makeJsResolveImportTarget` (TS resolver, JS extensions)
|
||||
*
|
||||
* See `./index.ts` for the full per-module rationale.
|
||||
*
|
||||
* ## Key differences from TypeScript resolver
|
||||
*
|
||||
* - `fieldFallbackOnMethodLookup: true` — JavaScript is dynamically typed;
|
||||
* the field-fallback heuristic is ENABLED (unlike TypeScript, which
|
||||
* disables it because the type-binding layer is precise).
|
||||
* - `allowGlobalFreeCallFallback: true` — CJS `require` patterns and
|
||||
* global helpers (e.g. `process`, `console`) benefit from workspace-
|
||||
* wide unique-name fallback. TypeScript uses explicit imports.
|
||||
* - `loadResolutionConfig` is omitted — JavaScript projects don't use
|
||||
* `tsconfig.json` path aliases in general. `tsconfigPaths: null` is
|
||||
* threaded through the resolver adapter.
|
||||
* - `hoistTypeBindingsToModule: true` — JSDoc `@returns {T}` bindings are
|
||||
* synthesized on the function scope and hoisted, matching TypeScript's
|
||||
* method return-type hoisting strategy for cross-file chain resolution.
|
||||
*/
|
||||
|
||||
import type { ParsedFile } from 'gitnexus-shared';
|
||||
import { SupportedLanguages } from 'gitnexus-shared';
|
||||
import { buildMro, defaultLinearize } from '../../scope-resolution/passes/mro.js';
|
||||
import { populateClassOwnedMembers } from '../../scope-resolution/scope/walkers.js';
|
||||
import type { ScopeResolver } from '../../scope-resolution/contract/scope-resolver.js';
|
||||
import { javascriptProvider } from '../typescript.js';
|
||||
import { jsMergeBindings } from './merge-bindings.js';
|
||||
import { jsArityCompatibility } from './arity.js';
|
||||
import { makeJsResolveImportTarget } from './import-target.js';
|
||||
|
||||
const javascriptScopeResolver: ScopeResolver = {
|
||||
language: SupportedLanguages.JavaScript,
|
||||
languageProvider: javascriptProvider,
|
||||
importEdgeReason: 'javascript-scope: import',
|
||||
|
||||
resolveImportTarget: makeJsResolveImportTarget(),
|
||||
|
||||
// JavaScript LEGB — same tier ordering as TypeScript; no declaration-
|
||||
// merging across type/value/namespace spaces.
|
||||
mergeBindings: (existing, incoming) => [...jsMergeBindings([...existing, ...incoming])],
|
||||
|
||||
// Adapter: jsArityCompatibility uses (def, callsite); contract is (callsite, def).
|
||||
arityCompatibility: (callsite, def) => jsArityCompatibility(def, callsite),
|
||||
|
||||
buildMro: (graph, parsedFiles, nodeLookup) =>
|
||||
buildMro(graph, parsedFiles, nodeLookup, defaultLinearize),
|
||||
|
||||
populateOwners: (parsed: ParsedFile) => populateClassOwnedMembers(parsed),
|
||||
|
||||
// JavaScript `super` keyword: same pattern as TypeScript.
|
||||
isSuperReceiver: (text) => /^super(\s*\(|\s*\.|\s*\[|\s*$)/.test(text.trim()),
|
||||
|
||||
// JavaScript is dynamically typed — enable the field-fallback heuristic
|
||||
// so member-call receivers without type annotations can still resolve
|
||||
// through declared class fields (e.g. JSDoc-typed fields).
|
||||
fieldFallbackOnMethodLookup: true,
|
||||
|
||||
// Return-type propagation (across ESM imports) mirrors TypeScript's
|
||||
// default behavior. JSDoc @returns bindings are hoisted to Module scope
|
||||
// and propagated to importers via the standard mechanism.
|
||||
propagatesReturnTypesAcrossImports: true,
|
||||
|
||||
// JSDoc @returns bindings are synthesized on the function/method node
|
||||
// and hoisted to Module scope by `jsBindingScopeFor` (identical to the
|
||||
// TypeScript `tsBindingScopeFor` `@type-binding.return` branch).
|
||||
hoistTypeBindingsToModule: true,
|
||||
|
||||
// CJS-heavy codebases often have utility functions exported without
|
||||
// explicit imports at the call site. Workspace-wide unique-name fallback
|
||||
// recovers these edges.
|
||||
allowGlobalFreeCallFallback: true,
|
||||
};
|
||||
|
||||
export { javascriptScopeResolver };
|
||||
|
|
@ -0,0 +1,48 @@
|
|||
/**
|
||||
* Simple hooks for the JavaScript scope-resolution provider.
|
||||
*
|
||||
* `jsBindingScopeFor` wraps `tsBindingScopeFor` and adds the JS-only
|
||||
* `@type-binding.class-field` hoisting rule. The other two hooks
|
||||
* (`jsImportOwningScope`, `jsReceiverBinding`) are identical to their
|
||||
* TypeScript counterparts and are re-exported directly.
|
||||
*
|
||||
* ## Why class-field hoisting lives here (not in `tsBindingScopeFor`)
|
||||
*
|
||||
* `@type-binding.class-field` is emitted exclusively by
|
||||
* `synthesizeConstructorFieldBindings` in `captures.ts`, which is a
|
||||
* JavaScript-only synthesis pass. TypeScript uses
|
||||
* `@type-binding.parameter-property` for constructor parameter
|
||||
* properties instead. Keeping the JS-only rule in the JS hook file
|
||||
* prevents language-specific logic from leaking into shared TypeScript
|
||||
* infrastructure (DoD.md §2.2).
|
||||
*/
|
||||
|
||||
import type { CaptureMatch, Scope, ScopeId, ScopeTree } from 'gitnexus-shared';
|
||||
import { tsBindingScopeFor, walkToScope } from '../typescript/simple-hooks.js';
|
||||
|
||||
export {
|
||||
tsImportOwningScope as jsImportOwningScope,
|
||||
tsReceiverBinding as jsReceiverBinding,
|
||||
} from '../typescript/simple-hooks.js';
|
||||
|
||||
/**
|
||||
* Like `tsBindingScopeFor` but additionally hoists
|
||||
* `@type-binding.class-field` captures to the enclosing Class scope.
|
||||
*
|
||||
* `@type-binding.class-field` is anchored inside the constructor body
|
||||
* (by `synthesizeConstructorFieldBindings`) so that `walkToScope` can
|
||||
* walk up from the Function (constructor) scope to the Class scope.
|
||||
* This puts `User.address → Address` in the class's typeBindings so
|
||||
* compound-receiver resolution finds it when resolving
|
||||
* `user.address.save()`.
|
||||
*/
|
||||
export function jsBindingScopeFor(
|
||||
decl: CaptureMatch,
|
||||
innermost: Scope,
|
||||
tree: ScopeTree,
|
||||
): ScopeId | null {
|
||||
if (decl['@type-binding.class-field'] !== undefined) {
|
||||
return walkToScope(innermost, tree, 'Class');
|
||||
}
|
||||
return tsBindingScopeFor(decl, innermost, tree);
|
||||
}
|
||||
|
|
@ -56,6 +56,16 @@ import {
|
|||
typescriptArityCompatibility,
|
||||
resolveTsImportTarget,
|
||||
} from './typescript/index.js';
|
||||
import {
|
||||
emitJsScopeCaptures,
|
||||
interpretJsImport,
|
||||
interpretJsTypeBinding,
|
||||
jsBindingScopeFor,
|
||||
jsImportOwningScope,
|
||||
jsReceiverBinding,
|
||||
jsMergeBindings,
|
||||
jsArityCompatibility,
|
||||
} from './javascript/index.js';
|
||||
|
||||
/**
|
||||
* TypeScript/JavaScript: arrow_function and function_expression are
|
||||
|
|
@ -359,4 +369,19 @@ export const javascriptProvider = defineLanguage({
|
|||
classExtractor: createClassExtractor(javascriptClassConfig),
|
||||
heritageExtractor: createHeritageExtractor(SupportedLanguages.JavaScript),
|
||||
builtInNames: BUILT_INS,
|
||||
|
||||
// ── RFC #909 Ring 3: scope-based resolution hooks (RFC §5) ──────────
|
||||
// JavaScript is the fourth migration after Python, C#, and TypeScript.
|
||||
// Hooks are thin wrappers over the TypeScript implementations where
|
||||
// semantics are identical; JS-specific additions (CJS require(),
|
||||
// JSDoc type bindings) live in ./javascript/captures.ts.
|
||||
// See ./javascript/index.ts for the full per-module rationale.
|
||||
emitScopeCaptures: emitJsScopeCaptures,
|
||||
interpretImport: interpretJsImport,
|
||||
interpretTypeBinding: interpretJsTypeBinding,
|
||||
bindingScopeFor: jsBindingScopeFor,
|
||||
importOwningScope: jsImportOwningScope,
|
||||
mergeBindings: (_scope, bindings) => jsMergeBindings(bindings),
|
||||
receiverBinding: jsReceiverBinding,
|
||||
arityCompatibility: jsArityCompatibility,
|
||||
});
|
||||
|
|
|
|||
|
|
@ -64,7 +64,7 @@ const CALL_TAGS = [
|
|||
'@reference.call.constructor',
|
||||
] as const;
|
||||
|
||||
function pickFirstDefined(grouped: CaptureMatch, tags: readonly string[]): Capture | undefined {
|
||||
function pickFirstCapture(grouped: CaptureMatch, tags: readonly string[]): Capture | undefined {
|
||||
for (const tag of tags) {
|
||||
const cap = grouped[tag];
|
||||
if (cap !== undefined) return cap;
|
||||
|
|
@ -72,6 +72,17 @@ function pickFirstDefined(grouped: CaptureMatch, tags: readonly string[]): Captu
|
|||
return undefined;
|
||||
}
|
||||
|
||||
function pickFirstNode(
|
||||
grouped: Record<string, SyntaxNode | undefined>,
|
||||
tags: readonly string[],
|
||||
): SyntaxNode | undefined {
|
||||
for (const tag of tags) {
|
||||
const node = grouped[tag];
|
||||
if (node !== undefined) return node;
|
||||
}
|
||||
return undefined;
|
||||
}
|
||||
|
||||
/**
|
||||
* Drop `@reference.read.member` matches whose underlying `member_expression`
|
||||
* is NOT actually a read context:
|
||||
|
|
@ -113,6 +124,34 @@ function shouldEmitReadMember(memberNode: SyntaxNode): boolean {
|
|||
}
|
||||
}
|
||||
|
||||
/** Walks the parent chain from `node` (inclusive), returning the first node
|
||||
* whose type matches, or null. Faster than `findNodeAtRange` when the caller
|
||||
* already holds the anchor node — avoids re-scanning the tree from the root. */
|
||||
function findSelfOrAncestorOfType(node: SyntaxNode | undefined, type: string): SyntaxNode | null {
|
||||
if (node === undefined) return null;
|
||||
let current: SyntaxNode | null = node;
|
||||
while (current !== null) {
|
||||
if (current.type === type) return current;
|
||||
current = current.parent;
|
||||
}
|
||||
return null;
|
||||
}
|
||||
|
||||
/** Walks the parent chain from `node` (inclusive), returning the first node
|
||||
* whose type is in the set, or null. Plural form of {@link findSelfOrAncestorOfType}. */
|
||||
function findSelfOrAncestorOfTypes(
|
||||
node: SyntaxNode | undefined,
|
||||
types: readonly string[],
|
||||
): SyntaxNode | null {
|
||||
if (node === undefined) return null;
|
||||
let current: SyntaxNode | null = node;
|
||||
while (current !== null) {
|
||||
if (types.includes(current.type)) return current;
|
||||
current = current.parent;
|
||||
}
|
||||
return null;
|
||||
}
|
||||
|
||||
export function emitTsScopeCaptures(
|
||||
sourceText: string,
|
||||
filePath: string,
|
||||
|
|
@ -151,9 +190,11 @@ export function emitTsScopeCaptures(
|
|||
// `@`; we put it back so the central extractor's prefix lookups
|
||||
// (`@scope.`, `@declaration.`, …) work.
|
||||
const grouped: Record<string, Capture> = {};
|
||||
const groupedNodes: Record<string, SyntaxNode> = {};
|
||||
for (const c of m.captures) {
|
||||
const tag = '@' + c.name;
|
||||
grouped[tag] = nodeToCapture(tag, c.node);
|
||||
groupedNodes[tag] = c.node;
|
||||
}
|
||||
if (Object.keys(grouped).length === 0) continue;
|
||||
|
||||
|
|
@ -165,6 +206,10 @@ export function emitTsScopeCaptures(
|
|||
if (grouped['@import.statement'] !== undefined) {
|
||||
const stmtCapture = grouped['@import.statement'];
|
||||
const stmtNode =
|
||||
findSelfOrAncestorOfTypes(groupedNodes['@import.statement'], [
|
||||
'import_statement',
|
||||
'export_statement',
|
||||
]) ??
|
||||
findNodeAtRange(tree.rootNode, stmtCapture.range, 'import_statement') ??
|
||||
findNodeAtRange(tree.rootNode, stmtCapture.range, 'export_statement');
|
||||
if (stmtNode !== null) {
|
||||
|
|
@ -183,7 +228,9 @@ export function emitTsScopeCaptures(
|
|||
// `splitDynamicImport` branch consumes.
|
||||
if (grouped['@import.dynamic'] !== undefined) {
|
||||
const dynCapture = grouped['@import.dynamic'];
|
||||
const callNode = findNodeAtRange(tree.rootNode, dynCapture.range, 'call_expression');
|
||||
const callNode =
|
||||
findSelfOrAncestorOfType(groupedNodes['@import.dynamic'], 'call_expression') ??
|
||||
findNodeAtRange(tree.rootNode, dynCapture.range, 'call_expression');
|
||||
if (callNode !== null) {
|
||||
const decomposed = splitImportStatement(callNode);
|
||||
for (const d of decomposed) out.push(d);
|
||||
|
|
@ -197,7 +244,9 @@ export function emitTsScopeCaptures(
|
|||
// we rely on this emit-side filter so the query stays simple.
|
||||
if (grouped['@reference.read.member'] !== undefined) {
|
||||
const anchor = grouped['@reference.read.member'];
|
||||
const memberNode = findNodeAtRange(tree.rootNode, anchor.range, 'member_expression');
|
||||
const memberNode =
|
||||
findSelfOrAncestorOfType(groupedNodes['@reference.read.member'], 'member_expression') ??
|
||||
findNodeAtRange(tree.rootNode, anchor.range, 'member_expression');
|
||||
if (memberNode === null || !shouldEmitReadMember(memberNode)) {
|
||||
continue;
|
||||
}
|
||||
|
|
@ -208,9 +257,10 @@ export function emitTsScopeCaptures(
|
|||
// overloads — TypeScript supports overload signatures via
|
||||
// function_signature, so `parameterTypes` is populated when
|
||||
// available.
|
||||
const declAnchor = pickFirstDefined(grouped, FUNCTION_DECL_TAGS);
|
||||
const declAnchor = pickFirstCapture(grouped, FUNCTION_DECL_TAGS);
|
||||
const declAnchorNode = pickFirstNode(groupedNodes, FUNCTION_DECL_TAGS);
|
||||
if (declAnchor !== undefined) {
|
||||
const fnNode = findFunctionNode(tree.rootNode, declAnchor.range);
|
||||
const fnNode = findFunctionNode(tree.rootNode, declAnchor.range, declAnchorNode);
|
||||
if (fnNode !== null) {
|
||||
const arity = computeTsArityMetadata(fnNode);
|
||||
if (arity.parameterCount !== undefined) {
|
||||
|
|
@ -255,9 +305,11 @@ export function emitTsScopeCaptures(
|
|||
// calls to disambiguate by props-arity, a JSX-aware arity
|
||||
// synthesizer would need to count `jsx_attribute` children of the
|
||||
// opening tag instead of `arguments`.
|
||||
const callAnchor = pickFirstDefined(grouped, CALL_TAGS);
|
||||
const callAnchor = pickFirstCapture(grouped, CALL_TAGS);
|
||||
const callAnchorNode = pickFirstNode(groupedNodes, CALL_TAGS);
|
||||
if (callAnchor !== undefined && grouped['@reference.arity'] === undefined) {
|
||||
const callNode =
|
||||
findSelfOrAncestorOfTypes(callAnchorNode, ['call_expression', 'new_expression']) ??
|
||||
findNodeAtRange(tree.rootNode, callAnchor.range, 'call_expression') ??
|
||||
findNodeAtRange(tree.rootNode, callAnchor.range, 'new_expression');
|
||||
if (callNode !== null) {
|
||||
|
|
@ -293,7 +345,11 @@ export function emitTsScopeCaptures(
|
|||
// lookup instead of synthesis — covered by `tsReceiverBinding`.
|
||||
const scopeFnAnchor = grouped['@scope.function'];
|
||||
if (scopeFnAnchor !== undefined) {
|
||||
const fnNode = findFunctionNode(tree.rootNode, scopeFnAnchor.range);
|
||||
const fnNode = findFunctionNode(
|
||||
tree.rootNode,
|
||||
scopeFnAnchor.range,
|
||||
groupedNodes['@scope.function'],
|
||||
);
|
||||
if (fnNode !== null) {
|
||||
const synth = synthesizeTsReceiverBinding(fnNode);
|
||||
if (synth !== null) out.push(synth);
|
||||
|
|
@ -518,7 +574,13 @@ function inferArgType(argNode: SyntaxNode): string {
|
|||
* The `@scope.function` anchor range covers the whole node, but the
|
||||
* tag alone doesn't identify which node type among the many TS
|
||||
* function-likes. */
|
||||
function findFunctionNode(rootNode: SyntaxNode, range: Capture['range']): SyntaxNode | null {
|
||||
function findFunctionNode(
|
||||
rootNode: SyntaxNode,
|
||||
range: Capture['range'],
|
||||
anchorNode?: SyntaxNode,
|
||||
): SyntaxNode | null {
|
||||
const fromAnchor = findSelfOrAncestorOfTypes(anchorNode, FUNCTION_NODE_TYPES);
|
||||
if (fromAnchor !== null) return fromAnchor;
|
||||
for (const nodeType of FUNCTION_NODE_TYPES) {
|
||||
const n = findNodeAtRange(rootNode, range, nodeType);
|
||||
if (n !== null) return n;
|
||||
|
|
|
|||
|
|
@ -75,8 +75,11 @@ export function tsBindingScopeFor(
|
|||
* any of `kinds`. Returns the matching scope's id or `null` when no
|
||||
* ancestor matches (e.g., a return type binding emitted outside any
|
||||
* Module scope — shouldn't happen in well-formed input).
|
||||
*
|
||||
* Exported so language-specific hook wrappers (e.g. `jsBindingScopeFor`)
|
||||
* can reuse it without duplicating the traversal logic.
|
||||
*/
|
||||
function walkToScope(
|
||||
export function walkToScope(
|
||||
from: Scope,
|
||||
tree: ScopeTree,
|
||||
...kinds: readonly Scope['kind'][]
|
||||
|
|
|
|||
|
|
@ -832,6 +832,14 @@ const processParsingSequential = async (
|
|||
// Public API
|
||||
// ============================================================================
|
||||
|
||||
/**
|
||||
* Per-`WorkerPool` log-dedup state for quarantine reporting. Keyed on the
|
||||
* pool instance so multiple concurrent pools (test fixtures, future
|
||||
* multi-pool callers) each get their own seen-set. WeakMap entries vanish
|
||||
* when the pool is garbage-collected.
|
||||
*/
|
||||
const loggedQuarantineByPool = new WeakMap<WorkerPool, Set<string>>();
|
||||
|
||||
export const processParsing = async (
|
||||
graph: KnowledgeGraph,
|
||||
files: { path: string; content: string }[],
|
||||
|
|
@ -874,25 +882,75 @@ export const processParsing = async (
|
|||
`[scope-resolution prof] worker pool engaged for ${files.length} files — cross-phase tree cache will be empty; scope-resolution re-parses.`,
|
||||
);
|
||||
}
|
||||
try {
|
||||
return await processParsingWithWorkers(
|
||||
graph,
|
||||
files,
|
||||
symbolTable,
|
||||
astCache,
|
||||
workerPool,
|
||||
reportProgress,
|
||||
outRawResults,
|
||||
);
|
||||
} catch (err) {
|
||||
const message = err instanceof Error ? err.message : String(err);
|
||||
logger.warn({ message }, 'Worker pool parsing stopped; continuing with sequential parser:');
|
||||
reportProgress?.(
|
||||
lastProgress,
|
||||
files.length,
|
||||
`Sequential fallback after worker issue: ${message}`,
|
||||
);
|
||||
// U20 design pivot: the worker pool's resilience layers
|
||||
// (respawn budget, circuit breaker, quarantine, slot-attribution,
|
||||
// cumulative timeout) are the SOLE contract for handling worker
|
||||
// failures. There is no sequential-parser fallback for either
|
||||
// partial quarantine or full pool failure — the operator must see
|
||||
// a clear hard signal when workers can't recover, instead of a
|
||||
// silently-degraded graph from a possibly-crashing main-thread
|
||||
// sequential parser. A failing tree-sitter native binding that
|
||||
// quarantined a worker would, under the previous design, re-trigger
|
||||
// the same SIGSEGV on the main thread; we avoid that risk entirely.
|
||||
//
|
||||
// - Partial quarantine: the file is missing from this run's graph;
|
||||
// the per-chunk warn log below surfaces it; U2's chunk-cache
|
||||
// write-guard in parse-impl.ts keeps the chunk uncached so the
|
||||
// next analyze gets a cache miss and a fresh pool retries.
|
||||
// - Full pool failure: `WorkerPoolDispatchError` propagates from
|
||||
// `processParsingWithWorkers` up through this function. The
|
||||
// analyze run errors out instead of falling back to sequential.
|
||||
const data = await processParsingWithWorkers(
|
||||
graph,
|
||||
files,
|
||||
symbolTable,
|
||||
astCache,
|
||||
workerPool,
|
||||
reportProgress,
|
||||
outRawResults,
|
||||
);
|
||||
// Session-scoped quarantine (worker-pool resilience Layer 3): surface
|
||||
// any files this pool has decided are unsafe for workers so the
|
||||
// operator can see what was skipped. The pool already filtered them
|
||||
// out of dispatch; we only need to log + progress-report. Quarantine
|
||||
// is session-scoped per pool instance — a fresh `createWorkerPool`
|
||||
// call clears it.
|
||||
//
|
||||
// Dedup: log full path list only for entries newly quarantined since
|
||||
// the previous dispatch on the same pool. The per-chunk progress
|
||||
// message still surfaces the count for UX continuity, but the
|
||||
// structured `quarantinedFiles` payload is only emitted when there
|
||||
// is new signal — prevents O(quarantine × chunks) log spam.
|
||||
const quarantineSnapshot = workerPool.getQuarantinedPaths?.() ?? [];
|
||||
const quarantineSet = new Set(quarantineSnapshot);
|
||||
if (quarantineSet.size > 0) {
|
||||
const quarantinedInChunk = files.filter((file) => quarantineSet.has(file.path));
|
||||
if (quarantinedInChunk.length > 0) {
|
||||
const seenForPool = loggedQuarantineByPool.get(workerPool) ?? new Set<string>();
|
||||
const newlyQuarantined = quarantinedInChunk
|
||||
.map((file) => file.path)
|
||||
.filter((p) => !seenForPool.has(p));
|
||||
for (const p of newlyQuarantined) seenForPool.add(p);
|
||||
loggedQuarantineByPool.set(workerPool, seenForPool);
|
||||
if (newlyQuarantined.length > 0) {
|
||||
logger.warn(
|
||||
{
|
||||
newlyQuarantined,
|
||||
cumulativeQuarantine: quarantineSet.size,
|
||||
chunkSkipped: quarantinedInChunk.length,
|
||||
},
|
||||
`Worker quarantine: ${newlyQuarantined.length} new file(s) skipped this chunk ` +
|
||||
`(${quarantinedInChunk.length} skipped total, ${quarantineSet.size} cumulative).`,
|
||||
);
|
||||
}
|
||||
reportProgress?.(
|
||||
lastProgress,
|
||||
files.length,
|
||||
`${quarantinedInChunk.length} worker-quarantined file(s) skipped`,
|
||||
);
|
||||
}
|
||||
}
|
||||
return data;
|
||||
}
|
||||
|
||||
// Fallback: sequential parsing (no pre-extracted data)
|
||||
|
|
|
|||
|
|
@ -55,6 +55,7 @@ import type {
|
|||
ExtractedCall,
|
||||
ExtractedDecoratorRoute,
|
||||
ExtractedFetchCall,
|
||||
ExtractedImport,
|
||||
ExtractedORMQuery,
|
||||
ExtractedRoute,
|
||||
ExtractedToolDef,
|
||||
|
|
@ -69,6 +70,7 @@ import path from 'node:path';
|
|||
import { fileURLToPath, pathToFileURL } from 'node:url';
|
||||
|
||||
import { isDev } from '../utils/env.js';
|
||||
import { isVerboseIngestionEnabled } from '../utils/verbose.js';
|
||||
import { synthesizeWildcardImportBindings, needsSynthesis } from './wildcard-synthesis.js';
|
||||
import { extractORMQueriesInline } from './orm-extraction.js';
|
||||
|
||||
|
|
@ -85,11 +87,24 @@ import { logger } from '../../logger.js';
|
|||
* gives a useful invalidation floor (~1/N chunks on a multi-MB repo)
|
||||
* while keeping worker dispatch overhead under 5% on cold runs.
|
||||
*/
|
||||
const CHUNK_BYTE_BUDGET = (() => {
|
||||
/**
|
||||
* Built-in chunk byte budget when neither `PipelineOptions.chunkByteBudget`
|
||||
* nor `GITNEXUS_CHUNK_BYTE_BUDGET` is set. Tuned to give a useful
|
||||
* cache-invalidation floor (~1/N chunks on a multi-MB repo) while keeping
|
||||
* worker dispatch overhead under 5% on cold runs. Resolution happens at
|
||||
* call time inside `runChunkedParseAndResolve` (U14 from PR #1693 review)
|
||||
* — previously this was a module-load IIFE, which froze the env value at
|
||||
* import time and meant per-call option threading silently no-op'd.
|
||||
*/
|
||||
const DEFAULT_CHUNK_BYTE_BUDGET = 2 * 1024 * 1024;
|
||||
|
||||
function resolveChunkByteBudget(options?: PipelineOptions): number {
|
||||
const opt = options?.chunkByteBudget;
|
||||
if (typeof opt === 'number' && Number.isFinite(opt) && opt > 0) return opt;
|
||||
const env = Number(process.env.GITNEXUS_CHUNK_BYTE_BUDGET);
|
||||
if (Number.isFinite(env) && env > 0) return env;
|
||||
return 2 * 1024 * 1024;
|
||||
})();
|
||||
return DEFAULT_CHUNK_BYTE_BUDGET;
|
||||
}
|
||||
|
||||
// ── Main parse + resolve function ──────────────────────────────────────────
|
||||
|
||||
|
|
@ -177,18 +192,28 @@ export async function runChunkedParseAndResolve(
|
|||
if (totalParseable === 0) {
|
||||
onProgress({
|
||||
phase: 'parsing',
|
||||
percent: 82,
|
||||
// Skip directly to the end of the parse-phase progress band (M2 from PR
|
||||
// #1693 review). Parse 20-70%, deferred 70-95%; nothing in either runs
|
||||
// when there's no parseable file, so jump to 95.
|
||||
percent: 95,
|
||||
message: 'No parseable files found — skipping parsing phase',
|
||||
stats: { filesProcessed: 0, totalFiles: 0, nodesCreated: graph.nodeCount },
|
||||
});
|
||||
}
|
||||
|
||||
// Build byte-budget chunks
|
||||
// Build byte-budget chunks. The budget is resolved per-call (U14): options
|
||||
// first, then env, then the built-in default. Pre-U14 this was a
|
||||
// module-load IIFE constant, which froze the env value at import time
|
||||
// and made `PipelineOptions.chunkByteBudget` silently no-op on warm test
|
||||
// runs. Resolving in the function body restores per-call configurability
|
||||
// and matches the pattern used by resolveAutoPoolSize and the U1
|
||||
// parseChunkConcurrency resolver.
|
||||
const chunkByteBudget = resolveChunkByteBudget(options);
|
||||
const chunks: string[][] = [];
|
||||
let currentChunk: string[] = [];
|
||||
let currentBytes = 0;
|
||||
for (const file of parseableScanned) {
|
||||
if (currentChunk.length > 0 && currentBytes + file.size > CHUNK_BYTE_BUDGET) {
|
||||
if (currentChunk.length > 0 && currentBytes + file.size > chunkByteBudget) {
|
||||
chunks.push(currentChunk);
|
||||
currentChunk = [];
|
||||
currentBytes = 0;
|
||||
|
|
@ -203,16 +228,22 @@ export async function runChunkedParseAndResolve(
|
|||
if (isDev) {
|
||||
const totalMB = parseableScanned.reduce((s, f) => s + f.size, 0) / (1024 * 1024);
|
||||
logger.info(
|
||||
`📂 Scan: ${totalFiles} paths, ${totalParseable} parseable (${totalMB.toFixed(0)}MB), ${numChunks} chunks @ ${CHUNK_BYTE_BUDGET / (1024 * 1024)}MB budget`,
|
||||
`📂 Scan: ${totalFiles} paths, ${totalParseable} parseable (${totalMB.toFixed(0)}MB), ${numChunks} chunks @ ${chunkByteBudget / (1024 * 1024)}MB budget`,
|
||||
);
|
||||
}
|
||||
|
||||
onProgress({
|
||||
phase: 'parsing',
|
||||
percent: 20,
|
||||
message: `Parsing ${totalParseable} files in ${numChunks} chunk${numChunks !== 1 ? 's' : ''}...`,
|
||||
stats: { filesProcessed: 0, totalFiles: totalParseable, nodesCreated: graph.nodeCount },
|
||||
});
|
||||
// Skip the "Parsing N files..." announcement when there's nothing to parse
|
||||
// — the early-return branch above already emitted percent 95 ("skipping
|
||||
// parsing phase"), and emitting percent 20 here would regress the
|
||||
// progress stream non-monotonically (M2 from PR #1693 review).
|
||||
if (totalParseable > 0) {
|
||||
onProgress({
|
||||
phase: 'parsing',
|
||||
percent: 20,
|
||||
message: `Parsing ${totalParseable} files in ${numChunks} chunk${numChunks !== 1 ? 's' : ''}...`,
|
||||
stats: { filesProcessed: 0, totalFiles: totalParseable, nodesCreated: graph.nodeCount },
|
||||
});
|
||||
}
|
||||
|
||||
// Don't spawn workers for tiny repos — overhead exceeds benefit.
|
||||
// Test suites may lower the thresholds via `options.workerThresholdsForTest`
|
||||
|
|
@ -221,18 +252,33 @@ export async function runChunkedParseAndResolve(
|
|||
const MIN_BYTES_FOR_WORKERS = options?.workerThresholdsForTest?.minBytes ?? 512 * 1024;
|
||||
const totalBytes = parseableScanned.reduce((s, f) => s + f.size, 0);
|
||||
|
||||
// Create worker pool once, reuse across chunks
|
||||
// Create worker pool once, reuse across chunks.
|
||||
//
|
||||
// `workerPoolSize === 0` is a programmatic equivalent of `skipWorkers:
|
||||
// true` per the `PipelineOptions.workerPoolSize` contract. Short-
|
||||
// circuiting here avoids constructing a useless pool that rejects
|
||||
// every dispatch (with a `Worker pool parsing stopped` warn log per
|
||||
// chunk) just to fall back to the sequential path via the error
|
||||
// catch — the gate honors the docstring directly.
|
||||
let workerPool: WorkerPool | undefined;
|
||||
if (
|
||||
!options?.skipWorkers &&
|
||||
options?.workerPoolSize !== 0 &&
|
||||
(totalParseable >= MIN_FILES_FOR_WORKERS || totalBytes >= MIN_BYTES_FOR_WORKERS)
|
||||
) {
|
||||
try {
|
||||
let workerUrl = new URL('../workers/parse-worker.js', import.meta.url);
|
||||
// U20.U3 test-only injection: integration tests pass a custom
|
||||
// worker script URL via `workerUrlForTest` (mirrors the
|
||||
// `workerThresholdsForTest` precedent) so they can drive the
|
||||
// chunk-loop with deterministically-misbehaving workers without
|
||||
// mocking the module import graph. When unset, the normal src/
|
||||
// → dist/ resolution runs.
|
||||
let workerUrl =
|
||||
options?.workerUrlForTest ?? new URL('../workers/parse-worker.js', import.meta.url);
|
||||
// When running under vitest, import.meta.url points to src/ where no .js exists.
|
||||
// Fall back to the compiled dist/ worker so the pool can spawn real worker threads.
|
||||
const thisDir = fileURLToPath(new URL('.', import.meta.url));
|
||||
if (!fs.existsSync(fileURLToPath(workerUrl))) {
|
||||
if (!options?.workerUrlForTest && !fs.existsSync(fileURLToPath(workerUrl))) {
|
||||
const distWorker = path.resolve(
|
||||
thisDir,
|
||||
'..',
|
||||
|
|
@ -249,7 +295,7 @@ export async function runChunkedParseAndResolve(
|
|||
workerUrl = pathToFileURL(distWorker);
|
||||
}
|
||||
}
|
||||
workerPool = createWorkerPool(workerUrl);
|
||||
workerPool = createWorkerPool(workerUrl, options?.workerPoolSize);
|
||||
} catch (err) {
|
||||
logger.warn(
|
||||
{ err: (err as Error).message },
|
||||
|
|
@ -301,6 +347,16 @@ export async function runChunkedParseAndResolve(
|
|||
const deferredWorkerHeritage: ExtractedHeritage[] = [];
|
||||
const deferredConstructorBindings: FileConstructorBindings[] = [];
|
||||
const deferredAssignments: ExtractedAssignment[] = [];
|
||||
// Imports accumulated across chunks. Previously processed per-chunk
|
||||
// via `processImportsFromExtracted` inside the chunk loop, which
|
||||
// forced workers to sit idle on the main thread's extraction pass
|
||||
// between chunk dispatches (4-5% CPU utilization symptom). Deferring
|
||||
// to a single end-of-loop pass lets the worker pool start chunk N+1
|
||||
// immediately after chunk N's worker dispatch returns. Resolution is
|
||||
// strictly-more-information at end-of-loop because graph now has
|
||||
// every chunk's symbols — improves cross-chunk import targets.
|
||||
const deferredWorkerImports: ExtractedImport[] = [];
|
||||
let anyChunkNeedsWildcardSynth = false;
|
||||
// Aggregated per-file ParsedFile artifacts produced by workers' calls
|
||||
// to `extractParsedFile`. Threaded through to the scope-resolution
|
||||
// phase so it can SKIP its own re-extraction on cache hits — this is
|
||||
|
|
@ -317,10 +373,54 @@ export async function runChunkedParseAndResolve(
|
|||
let chunkCacheMisses = 0;
|
||||
|
||||
try {
|
||||
// U1 — bounded chunk concurrency (B1 from PR #1693 review): pre-fetch
|
||||
// chunk file contents up to `parseChunkConcurrency` chunks ahead of the
|
||||
// dispatch cursor so file I/O overlaps with worker compute. Worker
|
||||
// dispatch itself stays serial because `WorkerPool.dispatch` is not
|
||||
// reentrant (concurrent calls would race on the shared per-slot
|
||||
// busy/in-flight state). With concurrency=1 behavior is identical to
|
||||
// the pure-serial loop. F4: deferred-state aggregation still happens
|
||||
// in chunkIdx order (the for-loop below iterates sequentially), so
|
||||
// cross-chunk processors see deterministic input regardless of
|
||||
// file-read completion order. Honors options.parseChunkConcurrency
|
||||
// (threaded from the CLI), then GITNEXUS_PARSE_CHUNK_CONCURRENCY env
|
||||
// (default 2 — matches the help text the CLI advertises).
|
||||
const parseChunkConcurrency = ((): number => {
|
||||
const opt = options?.parseChunkConcurrency;
|
||||
if (typeof opt === 'number' && Number.isInteger(opt) && opt >= 1) return opt;
|
||||
const env = Number(process.env.GITNEXUS_PARSE_CHUNK_CONCURRENCY);
|
||||
if (Number.isInteger(env) && env >= 1) return env;
|
||||
return 2;
|
||||
})();
|
||||
const chunkContentPromises = new Array<Promise<Map<string, string>> | undefined>(numChunks);
|
||||
const startChunkPrefetch = (i: number): void => {
|
||||
if (i >= numChunks || chunkContentPromises[i] !== undefined) return;
|
||||
chunkContentPromises[i] = readFileContents(repoPath, chunks[i]);
|
||||
};
|
||||
for (let i = 0; i < Math.min(parseChunkConcurrency, numChunks); i++) {
|
||||
startChunkPrefetch(i);
|
||||
}
|
||||
|
||||
// Hoisted loop-invariant: GITNEXUS_VERBOSE / NODE_ENV are read once
|
||||
// (not on every chunk). Previously evaluated at the top of the loop
|
||||
// body, which re-read process.env on every iteration even though
|
||||
// the env can't change mid-run.
|
||||
const verboseThroughputLog = isDev || isVerboseIngestionEnabled();
|
||||
|
||||
for (let chunkIdx = 0; chunkIdx < numChunks; chunkIdx++) {
|
||||
const chunkPaths = chunks[chunkIdx];
|
||||
// Start wall-clock for the per-chunk throughput log emitted at end
|
||||
// of this iteration. The gate is computed once above; here we just
|
||||
// sample the clock if the gate is on. Computed when either
|
||||
// NODE_ENV=development OR the operator passed `--verbose`
|
||||
// (GITNEXUS_VERBOSE) — the previous `isDev`-only gate meant
|
||||
// operators running `gitnexus analyze --verbose` in production
|
||||
// never saw the log (M3 from PR #1693 review).
|
||||
const chunkStartMs: number | null = verboseThroughputLog ? Date.now() : null;
|
||||
|
||||
const chunkContents = await readFileContents(repoPath, chunkPaths);
|
||||
const chunkContents = await chunkContentPromises[chunkIdx]!;
|
||||
chunkContentPromises[chunkIdx] = undefined; // release the in-memory copy
|
||||
startChunkPrefetch(chunkIdx + parseChunkConcurrency);
|
||||
const chunkFiles = chunkPaths
|
||||
.filter((p) => chunkContents.has(p))
|
||||
.map((p) => ({ path: p, content: chunkContents.get(p)! }));
|
||||
|
|
@ -357,7 +457,11 @@ export async function runChunkedParseAndResolve(
|
|||
const cachedFiles = chunkFiles.length;
|
||||
onProgress({
|
||||
phase: 'parsing',
|
||||
percent: Math.round(20 + ((filesParsedSoFar + cachedFiles) / totalParseable) * 62),
|
||||
// Parse phase covers 20-70 (50 points). Deferred extraction below
|
||||
// takes 70-95 so the UI advances through the (potentially long)
|
||||
// resolution stages instead of holding at 82 (M2 from PR #1693
|
||||
// review).
|
||||
percent: Math.round(20 + ((filesParsedSoFar + cachedFiles) / totalParseable) * 50),
|
||||
message: `Parsing chunk ${chunkIdx + 1}/${numChunks} (cache)...`,
|
||||
stats: {
|
||||
filesProcessed: filesParsedSoFar + cachedFiles,
|
||||
|
|
@ -378,7 +482,8 @@ export async function runChunkedParseAndResolve(
|
|||
scopeTreeCache,
|
||||
(current, _total, filePath) => {
|
||||
const globalCurrent = filesParsedSoFar + current;
|
||||
const parsingProgress = 20 + (globalCurrent / totalParseable) * 62;
|
||||
// Parse phase covers 20-70 (M2). Deferred extraction handles 70-95.
|
||||
const parsingProgress = 20 + (globalCurrent / totalParseable) * 50;
|
||||
onProgress({
|
||||
phase: 'parsing',
|
||||
percent: Math.round(parsingProgress),
|
||||
|
|
@ -399,56 +504,63 @@ export async function runChunkedParseAndResolve(
|
|||
// Persist the raw results for this chunk hash. Sequential path
|
||||
// doesn't populate rawResults (it writes directly to graph), so
|
||||
// small repos without worker pool simply don't cache. That's fine.
|
||||
//
|
||||
// U20.U2: refuse the write when any chunk file is in the
|
||||
// worker pool's cumulative quarantine snapshot. The chunkHash
|
||||
// is computed from EVERY file in the chunk, but the pool's
|
||||
// Layer 3 quarantine filters quarantined files out of dispatch
|
||||
// — so `rawResults` is narrower than the chunkHash key implies.
|
||||
// Caching it would silently replay incomplete results on the
|
||||
// next run with unchanged content (the corruption class Codex's
|
||||
// adversarial review of PR #1693 flagged).
|
||||
//
|
||||
// Skipping the write means the next analyze gets a cache miss
|
||||
// for this chunk and re-dispatches against a fresh worker pool
|
||||
// (quarantine is session-scoped — `createQuarantine` is called
|
||||
// per-pool at worker-pool.ts), giving the quarantined file
|
||||
// another chance. If quarantine fires again, U20.U1's
|
||||
// sequential gap-fill still produces a complete graph for this
|
||||
// run; the cache just stays empty for this chunk until a fully-
|
||||
// clean dispatch lands.
|
||||
if (parseCache && chunkHash && rawResults.length > 0) {
|
||||
parseCache.entries.set(chunkHash, rawResults);
|
||||
if (isDev) {
|
||||
logger.info(
|
||||
`📦 parse-cache MISS+store: chunk ${chunkIdx + 1}/${numChunks} (${chunkFiles.length} files, ${chunkHash.slice(0, 8)})`,
|
||||
);
|
||||
const quarantineSnapshot = workerPool?.getQuarantinedPaths?.() ?? [];
|
||||
const quarantineSet = new Set(quarantineSnapshot);
|
||||
const chunkHadQuarantine = chunkFiles.some((f) => quarantineSet.has(f.path));
|
||||
if (chunkHadQuarantine) {
|
||||
if (isDev) {
|
||||
const quarantinedInChunk = chunkFiles.filter((f) => quarantineSet.has(f.path)).length;
|
||||
logger.info(
|
||||
`📦 parse-cache SKIP: chunk ${chunkIdx + 1}/${numChunks} ` +
|
||||
`had ${quarantinedInChunk} worker-quarantined file(s); ` +
|
||||
`next run will rediscover (${chunkHash.slice(0, 8)})`,
|
||||
);
|
||||
}
|
||||
} else {
|
||||
parseCache.entries.set(chunkHash, rawResults);
|
||||
if (isDev) {
|
||||
logger.info(
|
||||
`📦 parse-cache MISS+store: chunk ${chunkIdx + 1}/${numChunks} (${chunkFiles.length} files, ${chunkHash.slice(0, 8)})`,
|
||||
);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
const chunkBasePercent = 20 + (filesParsedSoFar / totalParseable) * 62;
|
||||
|
||||
// Per-chunk extraction passes (processImportsFromExtracted,
|
||||
// processHeritageFromExtracted, processRoutesFromExtracted,
|
||||
// synthesizeWildcardImportBindings, seedCrossFileReceiverTypes)
|
||||
// moved out of the chunk loop into a single end-of-loop pass below.
|
||||
// Reason: per-chunk extraction blocked the chunk loop on
|
||||
// main-thread work between worker dispatches — workers sat idle
|
||||
// and total CPU utilization plateaued at 4-5% on multi-core boxes.
|
||||
// Deferring keeps workers busy chunk-after-chunk; resolution sees
|
||||
// strictly-more-information (full repo graph) so cross-chunk import
|
||||
// and heritage targets resolve at least as well as before.
|
||||
if (chunkWorkerData) {
|
||||
await processImportsFromExtracted(
|
||||
graph,
|
||||
allPathObjects,
|
||||
chunkWorkerData.imports,
|
||||
ctx,
|
||||
(current, total) => {
|
||||
onProgress({
|
||||
phase: 'parsing',
|
||||
percent: Math.round(chunkBasePercent),
|
||||
message: `Resolving imports (chunk ${chunkIdx + 1}/${numChunks})...`,
|
||||
detail: `${current}/${total} files`,
|
||||
stats: {
|
||||
filesProcessed: filesParsedSoFar,
|
||||
totalFiles: totalParseable,
|
||||
nodesCreated: graph.nodeCount,
|
||||
},
|
||||
});
|
||||
},
|
||||
repoPath,
|
||||
importCtx,
|
||||
);
|
||||
if (chunkNeedsSynthesis[chunkIdx]) {
|
||||
synthesizeWildcardImportBindings(graph, ctx);
|
||||
hasSynthesized = true;
|
||||
}
|
||||
if (exportedTypeMap.size > 0 && ctx.namedImportMap.size > 0) {
|
||||
const { enrichedCount } = seedCrossFileReceiverTypes(
|
||||
chunkWorkerData.calls,
|
||||
ctx.namedImportMap,
|
||||
exportedTypeMap,
|
||||
);
|
||||
if (isDev && enrichedCount > 0) {
|
||||
logger.info(
|
||||
`🔗 E1: Seeded ${enrichedCount} cross-file receiver types (chunk ${chunkIdx + 1})`,
|
||||
);
|
||||
}
|
||||
anyChunkNeedsWildcardSynth = true;
|
||||
}
|
||||
for (const item of chunkWorkerData.imports) deferredWorkerImports.push(item);
|
||||
for (const item of chunkWorkerData.calls) deferredWorkerCalls.push(item);
|
||||
for (const item of chunkWorkerData.heritage) deferredWorkerHeritage.push(item);
|
||||
for (const item of chunkWorkerData.constructorBindings)
|
||||
|
|
@ -463,35 +575,6 @@ export async function runChunkedParseAndResolve(
|
|||
for (const item of chunkWorkerData.assignments) deferredAssignments.push(item);
|
||||
}
|
||||
|
||||
await Promise.all([
|
||||
processHeritageFromExtracted(graph, chunkWorkerData.heritage, ctx, (current, total) => {
|
||||
onProgress({
|
||||
phase: 'parsing',
|
||||
percent: Math.round(chunkBasePercent),
|
||||
message: `Resolving heritage (chunk ${chunkIdx + 1}/${numChunks})...`,
|
||||
detail: `${current}/${total} records`,
|
||||
stats: {
|
||||
filesProcessed: filesParsedSoFar,
|
||||
totalFiles: totalParseable,
|
||||
nodesCreated: graph.nodeCount,
|
||||
},
|
||||
});
|
||||
}),
|
||||
processRoutesFromExtracted(graph, chunkWorkerData.routes ?? [], ctx, (current, total) => {
|
||||
onProgress({
|
||||
phase: 'parsing',
|
||||
percent: Math.round(chunkBasePercent),
|
||||
message: `Resolving routes (chunk ${chunkIdx + 1}/${numChunks})...`,
|
||||
detail: `${current}/${total} routes`,
|
||||
stats: {
|
||||
filesProcessed: filesParsedSoFar,
|
||||
totalFiles: totalParseable,
|
||||
nodesCreated: graph.nodeCount,
|
||||
},
|
||||
});
|
||||
}),
|
||||
]);
|
||||
|
||||
if (chunkWorkerData.fileScopeBindings?.length) {
|
||||
for (const { filePath, bindings } of chunkWorkerData.fileScopeBindings) {
|
||||
if (typeof filePath !== 'string' || filePath.length === 0) continue;
|
||||
|
|
@ -530,6 +613,24 @@ export async function runChunkedParseAndResolve(
|
|||
|
||||
filesParsedSoFar += chunkFiles.length;
|
||||
astCache.clear();
|
||||
|
||||
// Throughput observability (U3): emit a per-chunk metrics line
|
||||
// under verbose ingestion mode so operators can verify CPU
|
||||
// utilization moved + tune `--workers` / batch sizes without
|
||||
// guessing. Cheap snapshot — just reads pool closure state.
|
||||
if (verboseThroughputLog && chunkStartMs !== null) {
|
||||
const elapsedMs = Date.now() - chunkStartMs;
|
||||
const filesPerSec = elapsedMs > 0 ? (chunkFiles.length * 1000) / elapsedMs : 0;
|
||||
const stats = workerPool?.getStats?.();
|
||||
const poolFrag = stats
|
||||
? ` pool: ${stats.activeSlots}/${stats.size} active, ` +
|
||||
`${stats.quarantined} quarantined${stats.poolBroken ? ', BROKEN' : ''}`
|
||||
: ' (sequential)';
|
||||
logger.info(
|
||||
`📊 chunk ${chunkIdx + 1}/${numChunks}: ${chunkFiles.length} files in ${elapsedMs}ms ` +
|
||||
`(${filesPerSec.toFixed(1)} files/s)${poolFrag}`,
|
||||
);
|
||||
}
|
||||
}
|
||||
|
||||
if (isDev && parseCache && (chunkCacheHits > 0 || chunkCacheMisses > 0)) {
|
||||
|
|
@ -538,10 +639,129 @@ export async function runChunkedParseAndResolve(
|
|||
);
|
||||
}
|
||||
|
||||
// Deferred end-of-loop extraction (moved out of the per-chunk block):
|
||||
// 1. processImportsFromExtracted on all chunks' imports
|
||||
// 2. synthesizeWildcardImportBindings (if any chunk had wildcards)
|
||||
// 3. seedCrossFileReceiverTypes on deferred calls (depends on
|
||||
// namedImportMap populated by step 1)
|
||||
// 4. processHeritageFromExtracted on all chunks' heritage
|
||||
// 5. processRoutesFromExtracted on all chunks' routes
|
||||
// Same logic as the prior per-chunk passes, just batched — resolution
|
||||
// sees the full repo graph instead of just current-and-earlier chunks.
|
||||
// Deferred extraction band (M2 from PR #1693 review): the 4 stages below
|
||||
// each get their own 5-10 point slice of the 70-95 range so percent
|
||||
// advances monotonically through the (potentially long) resolution work
|
||||
// instead of holding flat at 82. Stages that are skipped (zero-length
|
||||
// input) leave their band as a no-op jump — the next stage still starts
|
||||
// at its own band, preserving monotonicity.
|
||||
// imports: 70 -> 75 (5)
|
||||
// heritage: 75 -> 80 (5)
|
||||
// routes: 80 -> 85 (5)
|
||||
// calls: 85 -> 95 (10)
|
||||
if (deferredWorkerImports.length > 0) {
|
||||
await processImportsFromExtracted(
|
||||
graph,
|
||||
allPathObjects,
|
||||
deferredWorkerImports,
|
||||
ctx,
|
||||
(current, total) => {
|
||||
const ratio = total > 0 ? current / total : 1;
|
||||
onProgress({
|
||||
phase: 'parsing',
|
||||
percent: 70 + Math.round(ratio * 5),
|
||||
message: 'Resolving imports (all chunks)...',
|
||||
detail: `${current}/${total} files`,
|
||||
stats: {
|
||||
filesProcessed: filesParsedSoFar,
|
||||
totalFiles: totalParseable,
|
||||
nodesCreated: graph.nodeCount,
|
||||
},
|
||||
});
|
||||
},
|
||||
repoPath,
|
||||
importCtx,
|
||||
);
|
||||
// U15 (lightweight M1): processImportsFromExtracted is the sole
|
||||
// consumer of `deferredWorkerImports`. Free the array now so the
|
||||
// GC can reclaim the per-file ExtractedImport records before the
|
||||
// heavier downstream stages run (heritage, routes, calls). Peak
|
||||
// accumulator memory drops from O(repo) to O(repo - imports) for
|
||||
// the remainder of the deferred phase. The future per-chunk
|
||||
// streaming upgrade can rewrite this with the same correctness
|
||||
// contract once profile data shows it's warranted.
|
||||
deferredWorkerImports.length = 0;
|
||||
}
|
||||
if (anyChunkNeedsWildcardSynth) {
|
||||
synthesizeWildcardImportBindings(graph, ctx);
|
||||
hasSynthesized = true;
|
||||
}
|
||||
// L5 from PR #1693 review: populate `exportedTypeMap` from the in-progress
|
||||
// graph BEFORE `seedCrossFileReceiverTypes` runs. Previously the seeding
|
||||
// branch below was reached with `exportedTypeMap.size === 0` in the
|
||||
// worker path (the map was only built at the post-parse block far below,
|
||||
// AFTER the seeding branch), so the seed dead-coded itself silently and
|
||||
// call resolution never got the cross-file receiver-type enrichment.
|
||||
// The post-parse builder still runs as a defensive fallback on the
|
||||
// sequential path; its `size === 0` guard means we don't pay the cost
|
||||
// twice on the worker path.
|
||||
if (exportedTypeMap.size === 0 && graph.nodeCount > 0) {
|
||||
const graphExports = buildExportedTypeMapFromGraph(graph, ctx.model.symbols);
|
||||
for (const [fp, exports] of graphExports) exportedTypeMap.set(fp, exports);
|
||||
}
|
||||
if (exportedTypeMap.size > 0 && ctx.namedImportMap.size > 0 && deferredWorkerCalls.length > 0) {
|
||||
const { enrichedCount } = seedCrossFileReceiverTypes(
|
||||
deferredWorkerCalls,
|
||||
ctx.namedImportMap,
|
||||
exportedTypeMap,
|
||||
);
|
||||
if (isDev && enrichedCount > 0) {
|
||||
logger.info(`🔗 E1: Seeded ${enrichedCount} cross-file receiver types (all chunks)`);
|
||||
}
|
||||
}
|
||||
if (deferredWorkerHeritage.length > 0) {
|
||||
await processHeritageFromExtracted(graph, deferredWorkerHeritage, ctx, (current, total) => {
|
||||
const ratio = total > 0 ? current / total : 1;
|
||||
onProgress({
|
||||
phase: 'parsing',
|
||||
percent: 75 + Math.round(ratio * 5),
|
||||
message: 'Resolving heritage (all chunks)...',
|
||||
detail: `${current}/${total} records`,
|
||||
stats: {
|
||||
filesProcessed: filesParsedSoFar,
|
||||
totalFiles: totalParseable,
|
||||
nodesCreated: graph.nodeCount,
|
||||
},
|
||||
});
|
||||
});
|
||||
}
|
||||
if (allExtractedRoutes.length > 0) {
|
||||
await processRoutesFromExtracted(graph, allExtractedRoutes, ctx, (current, total) => {
|
||||
const ratio = total > 0 ? current / total : 1;
|
||||
onProgress({
|
||||
phase: 'parsing',
|
||||
percent: 80 + Math.round(ratio * 5),
|
||||
message: 'Resolving routes (all chunks)...',
|
||||
detail: `${current}/${total} routes`,
|
||||
stats: {
|
||||
filesProcessed: filesParsedSoFar,
|
||||
totalFiles: totalParseable,
|
||||
nodesCreated: graph.nodeCount,
|
||||
},
|
||||
});
|
||||
});
|
||||
}
|
||||
|
||||
const fullWorkerHeritageMap =
|
||||
deferredWorkerHeritage.length > 0
|
||||
? buildHeritageMap(deferredWorkerHeritage, ctx, getHeritageStrategyForLanguage)
|
||||
: undefined;
|
||||
// U15 (lightweight M1): buildHeritageMap is the LAST consumer of the
|
||||
// raw `deferredWorkerHeritage` records — processCallsFromExtracted
|
||||
// below reads from the derived `fullWorkerHeritageMap` instead. Free
|
||||
// the raw heritage array now so the GC can reclaim it before the
|
||||
// (potentially long) call-resolution stage. processHeritageFromExtracted
|
||||
// earlier was a read-only consumer (pushed to graph, didn't drain).
|
||||
deferredWorkerHeritage.length = 0;
|
||||
|
||||
if (deferredWorkerCalls.length > 0) {
|
||||
await processCallsFromExtracted(
|
||||
|
|
@ -549,9 +769,13 @@ export async function runChunkedParseAndResolve(
|
|||
deferredWorkerCalls,
|
||||
ctx,
|
||||
(current, total) => {
|
||||
const ratio = total > 0 ? current / total : 1;
|
||||
onProgress({
|
||||
phase: 'parsing',
|
||||
percent: 82,
|
||||
// Calls is the longest deferred stage on real repos — give it the
|
||||
// 10-point tail 85-95 so the progress bar visibly advances during
|
||||
// call resolution instead of holding at 82 (M2).
|
||||
percent: 85 + Math.round(ratio * 10),
|
||||
message: 'Resolving calls (all chunks)...',
|
||||
detail: `${current}/${total} files`,
|
||||
stats: {
|
||||
|
|
@ -576,6 +800,20 @@ export async function runChunkedParseAndResolve(
|
|||
bindingAccumulator,
|
||||
);
|
||||
}
|
||||
// U15 (lightweight M1): all three arrays have had their last consumer
|
||||
// by the time we reach this point — processCallsFromExtracted drained
|
||||
// `deferredWorkerCalls` and read `deferredConstructorBindings`;
|
||||
// processAssignmentsFromExtracted drained `deferredAssignments` and
|
||||
// also read `deferredConstructorBindings`. Free them now so the
|
||||
// function-scope references die before downstream graph-build /
|
||||
// scope-resolution starts using its own working memory. Note: arrays
|
||||
// returned in the function result object (allFetchCalls,
|
||||
// allExtractedRoutes, allDecoratorRoutes, allToolDefs, allORMQueries,
|
||||
// allParsedFiles) intentionally stay live — downstream consumers
|
||||
// need them.
|
||||
deferredWorkerCalls.length = 0;
|
||||
deferredConstructorBindings.length = 0;
|
||||
deferredAssignments.length = 0;
|
||||
} finally {
|
||||
await workerPool?.terminate();
|
||||
}
|
||||
|
|
|
|||
|
|
@ -55,6 +55,16 @@ export interface PipelineOptions {
|
|||
minFiles?: number;
|
||||
minBytes?: number;
|
||||
};
|
||||
/**
|
||||
* @internal Test-only override for the worker script URL the pool
|
||||
* spawns. When unset, parse-impl resolves `parse-worker.js` from the
|
||||
* adjacent `workers/` directory (or the compiled `dist/` fallback
|
||||
* under vitest). Integration tests use this to inject a custom
|
||||
* worker script that deterministically triggers worker-pool
|
||||
* resilience paths (e.g., crash-on-poison-file) — same precedent as
|
||||
* `workerThresholdsForTest`. Do not use from production call sites.
|
||||
*/
|
||||
workerUrlForTest?: URL;
|
||||
/**
|
||||
* Incremental-indexing parse cache. When provided:
|
||||
* - The parse phase looks up each chunk's content hash in
|
||||
|
|
@ -68,6 +78,46 @@ export interface PipelineOptions {
|
|||
* See `gitnexus/src/storage/parse-cache.ts`.
|
||||
*/
|
||||
parseCache?: import('../../storage/parse-cache.js').ParseCache;
|
||||
/**
|
||||
* Worker pool size override, threaded from the CLI `--workers` flag
|
||||
* via `AnalyzeOptions`. When set, parse-impl passes this directly to
|
||||
* `createWorkerPool` so the pool sizing bypasses the env-var fallback
|
||||
* in `resolveAutoPoolSize`. The env-var channel
|
||||
* (`GITNEXUS_WORKER_POOL_SIZE`) remains as a back-compat fallback when
|
||||
* this field is undefined. Setting `workerPoolSize: 0` disables the
|
||||
* pool entirely (sequential fallback) — equivalent to `skipWorkers`
|
||||
* but expressed in the same units as `--workers <N>` so long-running
|
||||
* hosts (eval-server, MCP daemon) can size per-call without leaking
|
||||
* `process.env` state across analyze invocations.
|
||||
*/
|
||||
workerPoolSize?: number;
|
||||
/**
|
||||
* Number of chunks whose file contents may be read into memory in
|
||||
* parallel while the worker pool is busy dispatching the current
|
||||
* chunk. Pre-fetching overlaps disk I/O for chunk N+1..N+K with the
|
||||
* worker compute on chunk N — modest but real wall-clock win on
|
||||
* repos large enough to chunk. Worker dispatch itself remains serial
|
||||
* because `WorkerPool.dispatch` is not reentrant (concurrent calls
|
||||
* would race on the shared per-slot busy/in-flight state).
|
||||
*
|
||||
* `1` matches today's pure-serial behavior; `2` is the documented
|
||||
* default (`GITNEXUS_PARSE_CHUNK_CONCURRENCY`). Falls back to the
|
||||
* env var when undefined; defaults to 2 when neither is set.
|
||||
*/
|
||||
parseChunkConcurrency?: number;
|
||||
/**
|
||||
* Byte budget per parse chunk (in bytes). When set, parse-impl uses
|
||||
* this instead of the `GITNEXUS_CHUNK_BYTE_BUDGET` env var or the
|
||||
* built-in 2 MB default. Smaller values produce more chunks (finer
|
||||
* cache-hit granularity, more worker dispatches); larger values
|
||||
* batch more files per dispatch.
|
||||
*
|
||||
* Threading the value through options instead of the env var lets
|
||||
* tests vary the chunk layout per-call without `vi.resetModules` and
|
||||
* lets long-running hosts (eval-server, MCP daemon) size per-call
|
||||
* without leaking `process.env` state across invocations.
|
||||
*/
|
||||
chunkByteBudget?: number;
|
||||
}
|
||||
|
||||
// ── Phase registry ─────────────────────────────────────────────────────────
|
||||
|
|
|
|||
|
|
@ -74,6 +74,7 @@ export const MIGRATED_LANGUAGES: ReadonlySet<SupportedLanguages> = new Set<Suppo
|
|||
SupportedLanguages.C,
|
||||
SupportedLanguages.CPlusPlus,
|
||||
SupportedLanguages.PHP,
|
||||
SupportedLanguages.JavaScript,
|
||||
]);
|
||||
|
||||
/**
|
||||
|
|
|
|||
|
|
@ -913,6 +913,9 @@ function pass5CollectReferences(
|
|||
const explicitReceiver = extractExplicitReceiver(match);
|
||||
const arity = extractArity(match);
|
||||
const argumentTypes = extractArgumentTypes(match);
|
||||
const argumentTypeClasses = parseJsonParameterTypeClassesCapture(
|
||||
match['@reference.parameter-type-classes'],
|
||||
);
|
||||
|
||||
const site: ReferenceSite = {
|
||||
name: nameCap.text,
|
||||
|
|
@ -923,6 +926,7 @@ function pass5CollectReferences(
|
|||
...(explicitReceiver !== undefined ? { explicitReceiver } : {}),
|
||||
...(arity !== undefined ? { arity } : {}),
|
||||
...(argumentTypes !== undefined ? { argumentTypes } : {}),
|
||||
...(argumentTypeClasses !== undefined ? { argumentTypeClasses } : {}),
|
||||
};
|
||||
referenceSites.push(site);
|
||||
}
|
||||
|
|
@ -1040,9 +1044,11 @@ const KNOWN_SUB_TAGS: ReadonlySet<string> = new Set<string>([
|
|||
'@reference.receiver',
|
||||
'@reference.arity',
|
||||
'@reference.parameter-types',
|
||||
'@reference.parameter-type-classes',
|
||||
'@declaration.parameter-count',
|
||||
'@declaration.required-parameter-count',
|
||||
'@declaration.parameter-types',
|
||||
'@declaration.parameter-type-classes',
|
||||
'@declaration.template-constraints',
|
||||
]);
|
||||
|
||||
|
|
|
|||
|
|
@ -17,7 +17,13 @@
|
|||
* generalization plan.
|
||||
*/
|
||||
|
||||
import type { ParsedFile, Reference, ScopeId, SymbolDefinition } from 'gitnexus-shared';
|
||||
import type {
|
||||
ParameterTypeClass,
|
||||
ParsedFile,
|
||||
Reference,
|
||||
ScopeId,
|
||||
SymbolDefinition,
|
||||
} from 'gitnexus-shared';
|
||||
import type { KnowledgeGraph } from '../../../graph/types.js';
|
||||
import type { ScopeResolutionIndexes } from '../../model/scope-resolution-indexes.js';
|
||||
import type { SemanticModel } from '../../model/semantic-model.js';
|
||||
|
|
@ -132,6 +138,7 @@ export function emitFreeCallFallback(
|
|||
site.arity,
|
||||
site.argumentTypes,
|
||||
{
|
||||
argumentTypeClasses: site.argumentTypeClasses,
|
||||
conversionRankFn: options.conversionRankFn,
|
||||
constraintCompatibility: options.constraintCompatibility,
|
||||
},
|
||||
|
|
@ -196,6 +203,7 @@ export function emitFreeCallFallback(
|
|||
fnDef = ordinary[0];
|
||||
} else {
|
||||
const narrowed = narrowOverloadCandidates(ordinary, site.arity, site.argumentTypes, {
|
||||
argumentTypeClasses: site.argumentTypeClasses,
|
||||
conversionRankFn: options.conversionRankFn,
|
||||
constraintCompatibility: options.constraintCompatibility,
|
||||
});
|
||||
|
|
@ -231,6 +239,7 @@ export function emitFreeCallFallback(
|
|||
push(adl);
|
||||
|
||||
const narrowed = narrowOverloadCandidates(merged, site.arity, site.argumentTypes, {
|
||||
argumentTypeClasses: site.argumentTypeClasses,
|
||||
conversionRankFn: options.conversionRankFn,
|
||||
constraintCompatibility: options.constraintCompatibility,
|
||||
});
|
||||
|
|
@ -274,6 +283,7 @@ export function emitFreeCallFallback(
|
|||
})
|
||||
: undefined,
|
||||
site.argumentTypes,
|
||||
site.argumentTypeClasses,
|
||||
options.conversionRankFn,
|
||||
);
|
||||
}
|
||||
|
|
@ -339,6 +349,7 @@ function pickUniqueGlobalCallable(
|
|||
callArity?: number,
|
||||
isCallerVisible?: (candidate: SymbolDefinition) => boolean,
|
||||
callArgTypes?: readonly string[],
|
||||
callArgTypeClasses?: readonly ParameterTypeClass[],
|
||||
conversionRankFn?: ConversionRankFn,
|
||||
): SymbolDefinition | undefined {
|
||||
const scopeDefs: SymbolDefinition[] = [];
|
||||
|
|
@ -377,6 +388,7 @@ function pickUniqueGlobalCallable(
|
|||
// disambiguate (e.g., `f(int)` vs `f(double)` called with `f(2.5)`).
|
||||
if (scopeDefs.length > 1) {
|
||||
const narrowed = narrowOverloadCandidates(scopeDefs, callArity, callArgTypes, {
|
||||
argumentTypeClasses: callArgTypeClasses,
|
||||
conversionRankFn,
|
||||
});
|
||||
if (narrowed.length === 1) return narrowed[0];
|
||||
|
|
@ -417,6 +429,7 @@ function pickUniqueGlobalCallable(
|
|||
// Same argument-type + conversion-rank narrowing for the model pool.
|
||||
if (defs.length > 1) {
|
||||
const narrowed = narrowOverloadCandidates(defs, callArity, callArgTypes, {
|
||||
argumentTypeClasses: callArgTypeClasses,
|
||||
conversionRankFn,
|
||||
});
|
||||
if (narrowed.length === 1) return narrowed[0];
|
||||
|
|
@ -490,6 +503,7 @@ export function pickImplicitThisOverload(
|
|||
readonly name: string;
|
||||
readonly arity?: number;
|
||||
readonly argumentTypes?: readonly string[];
|
||||
readonly argumentTypeClasses?: readonly import('gitnexus-shared').ParameterTypeClass[];
|
||||
},
|
||||
scopes: ScopeResolutionIndexes,
|
||||
workspaceIndex: WorkspaceResolutionIndex,
|
||||
|
|
@ -526,6 +540,7 @@ export function pickImplicitThisOverload(
|
|||
// disambiguating signal) leaves the call unresolved rather than
|
||||
// routing to an arbitrary first overload by registration order.
|
||||
const candidates = narrowOverloadCandidates(overloads, site.arity, site.argumentTypes, {
|
||||
argumentTypeClasses: site.argumentTypeClasses,
|
||||
conversionRankFn: hookCtx?.conversionRankFn,
|
||||
constraintCompatibility: hookCtx?.constraintCompatibility,
|
||||
});
|
||||
|
|
|
|||
|
|
@ -38,7 +38,13 @@
|
|||
* 5. Empty input returns empty output.
|
||||
*/
|
||||
|
||||
import type { ArityVerdict, Callsite, ConstraintContext, SymbolDefinition } from 'gitnexus-shared';
|
||||
import type {
|
||||
ArityVerdict,
|
||||
Callsite,
|
||||
ConstraintContext,
|
||||
ParameterTypeClass,
|
||||
SymbolDefinition,
|
||||
} from 'gitnexus-shared';
|
||||
|
||||
/**
|
||||
* Per-slot conversion-rank function. Returns a numeric cost for
|
||||
|
|
@ -51,7 +57,12 @@ import type { ArityVerdict, Callsite, ConstraintContext, SymbolDefinition } from
|
|||
* Each language provides its own implementation. The function operates
|
||||
* on normalized type strings (output of the language's type normalizer).
|
||||
*/
|
||||
export type ConversionRankFn = (argType: string, paramType: string) => number;
|
||||
export type ConversionRankFn = (
|
||||
argType: string,
|
||||
paramType: string,
|
||||
argTypeClass?: ParameterTypeClass,
|
||||
paramTypeClass?: ParameterTypeClass,
|
||||
) => number;
|
||||
|
||||
/**
|
||||
* Optional hook bundle for narrowing extension points. Threaded in
|
||||
|
|
@ -62,6 +73,8 @@ export type ConversionRankFn = (argType: string, paramType: string) => number;
|
|||
* undefined preserves the legacy arity + exact-type behavior.
|
||||
*/
|
||||
export interface OverloadNarrowingHookCtx {
|
||||
/** Shape-preserving per-argument sidecar aligned with `argTypes`. */
|
||||
readonly argumentTypeClasses?: ConstraintContext['argumentTypeClasses'];
|
||||
/** Conversion-rank scoring fallback (step 4b). Engages when the
|
||||
* exact-type filter rejects every candidate. */
|
||||
readonly conversionRankFn?: ConversionRankFn;
|
||||
|
|
@ -128,7 +141,16 @@ export function narrowOverloadCandidates(
|
|||
if (params === undefined) return false;
|
||||
for (let i = 0; i < argTypes.length && i < params.length; i++) {
|
||||
if (argTypes[i] === '') continue;
|
||||
if (argTypes[i] !== params[i]) return false;
|
||||
if (
|
||||
!exactTypeSlotMatches(
|
||||
argTypes[i],
|
||||
params[i],
|
||||
hookCtx?.argumentTypeClasses?.[i],
|
||||
d.parameterTypeClasses?.[i],
|
||||
)
|
||||
) {
|
||||
return false;
|
||||
}
|
||||
}
|
||||
return true;
|
||||
});
|
||||
|
|
@ -142,7 +164,12 @@ export function narrowOverloadCandidates(
|
|||
// are returned; multiple survivors are genuinely ambiguous. When
|
||||
// ranking also yields empty, fall through to the arity-filtered
|
||||
// `candidates` set — matches pre-#1606 behavior.
|
||||
const ranked = rankByConversion(candidates, argTypes, hookCtx.conversionRankFn);
|
||||
const ranked = rankByConversion(
|
||||
candidates,
|
||||
argTypes,
|
||||
hookCtx.conversionRankFn,
|
||||
hookCtx.argumentTypeClasses,
|
||||
);
|
||||
if (ranked.length > 0) result = ranked;
|
||||
}
|
||||
}
|
||||
|
|
@ -163,7 +190,15 @@ export function narrowOverloadCandidates(
|
|||
// than emitting a wrong edge.
|
||||
if (hookCtx?.constraintCompatibility !== undefined && argCount !== undefined) {
|
||||
const callsite: Callsite = { arity: argCount };
|
||||
const ctx: ConstraintContext = argTypes !== undefined ? { argumentTypes: argTypes } : {};
|
||||
const ctx: ConstraintContext =
|
||||
argTypes !== undefined
|
||||
? {
|
||||
argumentTypes: argTypes,
|
||||
...(hookCtx.argumentTypeClasses !== undefined
|
||||
? { argumentTypeClasses: hookCtx.argumentTypeClasses }
|
||||
: {}),
|
||||
}
|
||||
: {};
|
||||
result = result.filter((def) => {
|
||||
if (def.templateConstraints === undefined) return true;
|
||||
return hookCtx.constraintCompatibility!(callsite, def, ctx) !== 'incompatible';
|
||||
|
|
@ -173,6 +208,27 @@ export function narrowOverloadCandidates(
|
|||
return result;
|
||||
}
|
||||
|
||||
function exactTypeSlotMatches(
|
||||
argType: string,
|
||||
paramType: string,
|
||||
argTypeClass?: ParameterTypeClass,
|
||||
paramTypeClass?: ParameterTypeClass,
|
||||
): boolean {
|
||||
if (argType !== paramType) return false;
|
||||
// C++ normalizes away pointer markers (`int*` -> `int`). When both sides
|
||||
// provide shape sidecars, do not let that collapse make `int` exactly match
|
||||
// `int*`. Unknown sidecar evidence preserves the previous string-only path.
|
||||
if (argTypeClass === undefined || paramTypeClass === undefined) return true;
|
||||
if (argTypeClass.indirection === 'unknown' || paramTypeClass.indirection === 'unknown') {
|
||||
return true;
|
||||
}
|
||||
return isPointerShape(argTypeClass) === isPointerShape(paramTypeClass);
|
||||
}
|
||||
|
||||
function isPointerShape(typeClass: ParameterTypeClass): boolean {
|
||||
return typeClass.indirection === 'pointer' && typeClass.pointerDepth > 0;
|
||||
}
|
||||
|
||||
/**
|
||||
* Pairwise dominance comparison (ISO C++ [over.ics.rank]).
|
||||
*
|
||||
|
|
@ -189,6 +245,7 @@ function rankByConversion(
|
|||
candidates: readonly SymbolDefinition[],
|
||||
argTypes: readonly string[],
|
||||
rankFn: ConversionRankFn,
|
||||
argTypeClasses?: readonly ParameterTypeClass[],
|
||||
): readonly SymbolDefinition[] {
|
||||
// Step 1: compute per-slot ranks and exclude non-viable candidates.
|
||||
const viable: Array<{ def: SymbolDefinition; ranks: number[] }> = [];
|
||||
|
|
@ -197,12 +254,22 @@ function rankByConversion(
|
|||
if (params === undefined) continue;
|
||||
const ranks: number[] = [];
|
||||
let ok = true;
|
||||
for (let i = 0; i < argTypes.length && i < params.length; i++) {
|
||||
for (let i = 0; i < argTypes.length; i++) {
|
||||
const paramType = parameterTypeAt(params, i);
|
||||
if (paramType === undefined) {
|
||||
ok = false;
|
||||
break;
|
||||
}
|
||||
if (argTypes[i] === '') {
|
||||
ranks.push(0); // unknown arg → any-match (rank 0)
|
||||
continue;
|
||||
}
|
||||
const r = rankFn(argTypes[i], params[i]);
|
||||
const r = rankFn(
|
||||
argTypes[i],
|
||||
paramType,
|
||||
argTypeClasses?.[i],
|
||||
parameterTypeClassAt(d.parameterTypeClasses, i),
|
||||
);
|
||||
if (!isFinite(r)) {
|
||||
ok = false;
|
||||
break;
|
||||
|
|
@ -229,6 +296,20 @@ function rankByConversion(
|
|||
return viable.filter((_, idx) => !dominated.has(idx)).map((v) => v.def);
|
||||
}
|
||||
|
||||
function parameterTypeAt(params: readonly string[], argIndex: number): string | undefined {
|
||||
if (argIndex < params.length) return params[argIndex];
|
||||
return params[params.length - 1] === '...' ? '...' : undefined;
|
||||
}
|
||||
|
||||
function parameterTypeClassAt(
|
||||
params: readonly ParameterTypeClass[] | undefined,
|
||||
argIndex: number,
|
||||
): ParameterTypeClass | undefined {
|
||||
if (params === undefined) return undefined;
|
||||
if (argIndex < params.length) return params[argIndex];
|
||||
return params[params.length - 1]?.base === '...' ? params[params.length - 1] : undefined;
|
||||
}
|
||||
|
||||
/**
|
||||
* Compare two per-slot rank vectors.
|
||||
* Returns -1 if `a` dominates `b` (not worse everywhere, better somewhere),
|
||||
|
|
|
|||
|
|
@ -346,6 +346,7 @@ export function emitReceiverBoundCalls(
|
|||
site.arity,
|
||||
site.argumentTypes,
|
||||
{
|
||||
argumentTypeClasses: site.argumentTypeClasses,
|
||||
conversionRankFn: provider.conversionRankFn,
|
||||
constraintCompatibility: provider.constraintCompatibility,
|
||||
},
|
||||
|
|
@ -732,6 +733,7 @@ function pickOverload(
|
|||
if (overloads.length === 1) return overloads[0];
|
||||
|
||||
const candidates = narrowOverloadCandidates(overloads, site.arity, site.argumentTypes, {
|
||||
argumentTypeClasses: site.argumentTypeClasses,
|
||||
conversionRankFn: provider.conversionRankFn,
|
||||
constraintCompatibility: provider.constraintCompatibility,
|
||||
});
|
||||
|
|
|
|||
|
|
@ -19,6 +19,7 @@ import { javaScopeResolver } from '../../languages/java/scope-resolver.js';
|
|||
import { cScopeResolver } from '../../languages/c/scope-resolver.js';
|
||||
import { cppScopeResolver } from '../../languages/cpp/scope-resolver.js';
|
||||
import { phpScopeResolver } from '../../languages/php/scope-resolver.js';
|
||||
import { javascriptScopeResolver } from '../../languages/javascript/scope-resolver.js';
|
||||
|
||||
/** Map of `SupportedLanguages` → `ScopeResolver`. The phase iterates
|
||||
* this map intersected with `MIGRATED_LANGUAGES` (the per-language
|
||||
|
|
@ -36,4 +37,5 @@ export const SCOPE_RESOLVERS: ReadonlyMap<SupportedLanguages, ScopeResolver> = n
|
|||
[SupportedLanguages.C, cScopeResolver],
|
||||
[SupportedLanguages.CPlusPlus, cppScopeResolver],
|
||||
[SupportedLanguages.PHP, phpScopeResolver],
|
||||
[SupportedLanguages.JavaScript, javascriptScopeResolver],
|
||||
]);
|
||||
|
|
|
|||
|
|
@ -301,10 +301,7 @@ export interface ParseWorkerInput {
|
|||
content: string;
|
||||
}
|
||||
|
||||
type WorkerIncomingMessage =
|
||||
| { type: 'sub-batch'; files: ParseWorkerInput[] }
|
||||
| { type: 'flush' }
|
||||
| ParseWorkerInput[];
|
||||
type WorkerIncomingMessage = { type: 'sub-batch'; files: ParseWorkerInput[] } | { type: 'flush' };
|
||||
|
||||
// ============================================================================
|
||||
// Worker-local parser + language map
|
||||
|
|
@ -1401,6 +1398,15 @@ const processFileGroup = (
|
|||
// Skip files larger than the max tree-sitter buffer (32 MB)
|
||||
if (getTreeSitterContentByteLength(file.content) > TREE_SITTER_MAX_BUFFER) continue;
|
||||
|
||||
// Authoritative in-flight signal for the pool: lets `WorkerPool` exclude
|
||||
// exactly this file if the worker dies during parse/extract, instead of
|
||||
// guessing from `items[lastProgress]` (which the language-grouped order
|
||||
// here would defeat). The pool gracefully ignores this when running an
|
||||
// older worker build that doesn't emit it.
|
||||
if (parentPort) {
|
||||
parentPort.postMessage({ type: 'starting-file', path: file.path });
|
||||
}
|
||||
|
||||
// Vue SFC preprocessing: extract <script> block content
|
||||
let parseContent = file.content;
|
||||
let lineOffset = 0;
|
||||
|
|
@ -1458,8 +1464,11 @@ const processFileGroup = (
|
|||
parseContent,
|
||||
file.path,
|
||||
(message) => {
|
||||
if (parentPort) parentPort.postMessage({ type: 'warning', message });
|
||||
else logger.warn(message);
|
||||
if (parentPort) {
|
||||
parentPort.postMessage({ type: 'warning', message });
|
||||
} else {
|
||||
logger.warn(message);
|
||||
}
|
||||
},
|
||||
tree,
|
||||
);
|
||||
|
|
@ -2438,20 +2447,59 @@ const mergeResult = (target: ParseWorkerResult, src: ParseWorkerResult) => {
|
|||
target.fileCount += src.fileCount;
|
||||
};
|
||||
|
||||
// Signal the pool that worker-side initialization (parser imports, language
|
||||
// grammars, type-env setup, all helper modules) is complete and the message
|
||||
// handler below is about to be attached. The pool's `waitForWorkerReady`
|
||||
// resolves on this handshake — without it, a worker that crashes during
|
||||
// top-of-script init slips past pool startup (Node's `online` event fires
|
||||
// before the script body runs) and the pool only notices via the first
|
||||
// dispatch's idle timeout (~30s). Emit once; the dispatch handler treats
|
||||
// any subsequent `ready` message as a benign no-op.
|
||||
//
|
||||
// Native postMessage carries the ready handshake — Node's structured
|
||||
// clone delivers `{type:'ready'}` to the pool's waitForWorkerReady
|
||||
// listener directly. The pool drops the slot if this isn't seen within
|
||||
// `WORKER_READY_TIMEOUT_MS` (5s), so emitting it AFTER all top-of-script
|
||||
// init (imports, native binding loads, type-env setup) completes is the
|
||||
// load-bearing signal that this worker is ready for dispatch.
|
||||
parentPort!.postMessage({ type: 'ready' });
|
||||
|
||||
// Module-scope `TextDecoder` for sub-batch content. The pool sends each
|
||||
// file's content as a `Uint8Array` (zero-copy ArrayBuffer transfer); we
|
||||
// decode to string lazily here, once per file, before handing to
|
||||
// tree-sitter. Hoisted to module scope so we don't allocate a new
|
||||
// ICU-backed decoder per sub-batch — `TextDecoder.decode()` is
|
||||
// stateless across calls and safe to share.
|
||||
const sharedContentDecoder = new TextDecoder('utf-8');
|
||||
|
||||
/**
|
||||
* Convert the pool's sub-batch `files` array (content as `Uint8Array`,
|
||||
* transferred zero-copy) into the `ParseWorkerInput[]` shape
|
||||
* `processBatch` expects (content as `string`). This is the one place
|
||||
* the UTF-8 decode happens — runs on the worker thread in parallel with
|
||||
* continued main-thread work.
|
||||
*/
|
||||
function decodeSubBatchFiles(
|
||||
files: Array<{ path: string; content: Uint8Array | string }>,
|
||||
): ParseWorkerInput[] {
|
||||
return files.map((f) => ({
|
||||
path: f.path,
|
||||
// Test scaffolding (the writeReadyWorker preamble that wraps
|
||||
// parentPort.on) may already convert content to string before
|
||||
// calling here; tolerate both shapes so the same worker code
|
||||
// exercises real and synthetic dispatches.
|
||||
content: typeof f.content === 'string' ? f.content : sharedContentDecoder.decode(f.content),
|
||||
}));
|
||||
}
|
||||
|
||||
parentPort!.on('message', (msg: WorkerIncomingMessage) => {
|
||||
try {
|
||||
// Legacy single-message mode (backward compat): array of files
|
||||
if (Array.isArray(msg)) {
|
||||
const result = processBatch(msg, (filesProcessed) => {
|
||||
parentPort!.postMessage({ type: 'progress', filesProcessed });
|
||||
});
|
||||
parentPort!.postMessage({ type: 'result', data: result });
|
||||
return;
|
||||
}
|
||||
|
||||
// Sub-batch mode: { type: 'sub-batch', files: [...] }
|
||||
if (msg.type === 'sub-batch') {
|
||||
const result = processBatch(msg.files, (filesProcessed) => {
|
||||
const files = decodeSubBatchFiles(
|
||||
msg.files as Array<{ path: string; content: Uint8Array | string }>,
|
||||
);
|
||||
const result = processBatch(files, (filesProcessed) => {
|
||||
parentPort!.postMessage({
|
||||
type: 'progress',
|
||||
filesProcessed: cumulativeProcessed + filesProcessed,
|
||||
|
|
|
|||
59
gitnexus/src/core/ingestion/workers/quarantine.ts
Normal file
59
gitnexus/src/core/ingestion/workers/quarantine.ts
Normal file
|
|
@ -0,0 +1,59 @@
|
|||
/**
|
||||
* Quarantine layer (Layer 3 of the worker-pool resilience model).
|
||||
*
|
||||
* Tracks paths that caused a worker death this pool lifetime and must
|
||||
* not be re-dispatched to a worker. Session-scoped — created once per
|
||||
* `createWorkerPool` invocation and discarded with the pool.
|
||||
*
|
||||
* This module is the first piece of the U13 layer-extraction work. The
|
||||
* doc-review's A10 finding flagged the full 5-module split as
|
||||
* abstraction-without-multi-consumer-demand, so the rest of the
|
||||
* extraction is deferred until a real second consumer emerges (e.g., a
|
||||
* non-parse worker pool that reuses the same resilience layers).
|
||||
* Extracting the smallest self-contained layer first validates the
|
||||
* factory + interface pattern with minimal risk: behavior is unchanged,
|
||||
* the worker-pool.ts public API is unchanged, and existing tests act as
|
||||
* the regression net.
|
||||
*/
|
||||
|
||||
/**
|
||||
* Operations a {@link createQuarantine} instance exposes to the worker
|
||||
* pool. Intentionally tiny — anything more would invite the abstraction
|
||||
* overhead doc-review A10 cautioned against. Snapshot returns a fresh
|
||||
* `string[]` (not a `Set` or iterator) so callers can pass it directly
|
||||
* to `WorkerPoolDispatchError` without an `Array.from` dance and so
|
||||
* mutations to the returned array can't accidentally leak back into the
|
||||
* internal set.
|
||||
*/
|
||||
export interface Quarantine {
|
||||
/** Mark `path` as known-bad for the remainder of this pool's life. */
|
||||
add(path: string): void;
|
||||
/** Whether `path` has been quarantined. */
|
||||
has(path: string): boolean;
|
||||
/** Defensive copy of every quarantined path. */
|
||||
snapshot(): string[];
|
||||
/** How many distinct paths are currently quarantined. */
|
||||
readonly size: number;
|
||||
}
|
||||
|
||||
/**
|
||||
* Construct a fresh quarantine. Each `createWorkerPool` invocation gets
|
||||
* its own instance — quarantines never outlive the pool that created
|
||||
* them. The implementation is a thin wrapper around `Set<string>`; the
|
||||
* named interface exists to make the resilience layer addressable as a
|
||||
* unit (named module, dedicated tests) instead of an inline Set field
|
||||
* tangled into 1100+ LOC of pool plumbing.
|
||||
*/
|
||||
export function createQuarantine(): Quarantine {
|
||||
const paths = new Set<string>();
|
||||
return {
|
||||
add: (path) => {
|
||||
paths.add(path);
|
||||
},
|
||||
has: (path) => paths.has(path),
|
||||
snapshot: () => Array.from(paths),
|
||||
get size() {
|
||||
return paths.size;
|
||||
},
|
||||
};
|
||||
}
|
||||
File diff suppressed because it is too large
Load diff
|
|
@ -1651,7 +1651,10 @@ export const createFTSIndex = async (
|
|||
if (ensuredFTSIndexes.has(key)) return;
|
||||
|
||||
if (!(await loadFTSExtension())) {
|
||||
return;
|
||||
throw new Error(
|
||||
`FTS extension unavailable - cannot create FTS index ${tableName}.${indexName}. ` +
|
||||
'Run `gitnexus doctor` and ensure the LadybugDB FTS extension is installed and loadable on this machine.',
|
||||
);
|
||||
}
|
||||
|
||||
const propList = properties.map((p) => `'${p}'`).join(', ');
|
||||
|
|
|
|||
|
|
@ -16,6 +16,8 @@
|
|||
*/
|
||||
|
||||
import fs from 'fs/promises';
|
||||
import os from 'os';
|
||||
import path from 'path';
|
||||
import lbug from '@ladybugdb/core';
|
||||
import { isReadOnlyDbError, loadFTSExtension } from './lbug-adapter.js';
|
||||
import {
|
||||
|
|
@ -24,6 +26,42 @@ import {
|
|||
WAL_RECOVERY_SUGGESTION,
|
||||
} from './lbug-config.js';
|
||||
|
||||
/**
|
||||
* Probe whether a Windows FTS extension binary is locally installed under
|
||||
* ~/.lbdb/extension/<any-version>/win_amd64/fts/. Returns true on the first
|
||||
* version dir whose libfts.lbug_extension exists on disk; false if the
|
||||
* extension root is missing or contains no FTS binary.
|
||||
*
|
||||
* Gates the Windows skip-FTS-load guard below so we only skip the load
|
||||
* when no extension binary is present. When at least one binary exists,
|
||||
* loadFTSExtension is called with policy: 'load-only' — LadybugDB resolves
|
||||
* LOAD EXTENSION fts to its version-specific path internally, and the
|
||||
* ExtensionManager's tryLoad try/catch handles version-mismatch errors
|
||||
* cleanly without ever attempting dlopen of a stale binary. The install
|
||||
* path that the #1199/#1217 SIGSEGV documented is never exercised at
|
||||
* query time.
|
||||
*
|
||||
* Exported so unit tests can exercise the probe directly against a
|
||||
* temp-dir plus spied `os.homedir()` — see lbug-pool-win-fts-probe.test.ts.
|
||||
*/
|
||||
export async function hasLocalWinFtsExtension(): Promise<boolean> {
|
||||
try {
|
||||
const extRoot = path.join(os.homedir(), '.lbdb', 'extension');
|
||||
const versions = await fs.readdir(extRoot);
|
||||
for (const v of versions) {
|
||||
try {
|
||||
await fs.stat(path.join(extRoot, v, 'win_amd64', 'fts', 'libfts.lbug_extension'));
|
||||
return true;
|
||||
} catch {
|
||||
/* missing for this version, keep looking */
|
||||
}
|
||||
}
|
||||
} catch {
|
||||
/* no .lbdb/extension dir */
|
||||
}
|
||||
return false;
|
||||
}
|
||||
|
||||
/** Per-repo pool: one Database, many Connections */
|
||||
interface PoolEntry {
|
||||
db: lbug.Database;
|
||||
|
|
@ -423,14 +461,24 @@ async function doInitLbug(repoId: string, dbPath: string): Promise<void> {
|
|||
// install; analyze owns extension installation. If LOAD fails, search
|
||||
// features degrade gracefully and the user-facing query path proceeds.
|
||||
if (!shared.ftsLoaded) {
|
||||
// Windows guard: LOAD EXTENSION fts crashes with SIGSEGV on Windows when
|
||||
// the FTS extension binary is not installed locally (@ladybugdb/core native
|
||||
// bug — the extension loader hits an unhandled error path that signals SIGSEGV
|
||||
// rather than throwing a JS exception, so try/catch cannot protect here).
|
||||
// Skip the load on Windows; bm25-index.js catches the resulting Kuzu catalog
|
||||
// errors and returns empty BM25 results gracefully. Graph queries are unaffected.
|
||||
// Windows guard: LOAD EXTENSION fts crashes with SIGSEGV on Windows during
|
||||
// *install* — the @ladybugdb/core out-of-process installer hits an unhandled
|
||||
// error path that signals SIGSEGV instead of throwing (see #1199, #1217).
|
||||
// The previous unconditional skip was over-broad: it also disabled FTS on
|
||||
// hosts where the binary was already on disk and only needed LOAD, leaving
|
||||
// BM25 silently degraded with no error path (see #1690).
|
||||
//
|
||||
// Probe ~/.lbdb/extension/*/win_amd64/fts/ first. If any binary is on disk
|
||||
// we run loadFTSExtension(..., 'load-only'); the install path is never
|
||||
// exercised, and LadybugDB's version-specific resolution + ExtensionManager
|
||||
// try/catch handle stale/zero-byte siblings cleanly (verified empirically
|
||||
// on Win10 + Node 22.19 + gitnexus 1.6.5 + @ladybugdb/core 0.16.1). With
|
||||
// no binary at all, we fall back to the upstream skip so install-time
|
||||
// SIGSEGV continues to be avoided.
|
||||
if (process.platform === 'win32') {
|
||||
shared.ftsLoaded = true;
|
||||
shared.ftsLoaded = (await hasLocalWinFtsExtension())
|
||||
? await loadFTSExtension(available[0], { policy: 'load-only' })
|
||||
: true;
|
||||
} else {
|
||||
shared.ftsLoaded = await loadFTSExtension(available[0], { policy: 'load-only' });
|
||||
}
|
||||
|
|
@ -497,10 +545,12 @@ export async function initLbugWithDb(
|
|||
// Load FTS extension if not already loaded on this Database.
|
||||
// policy: 'load-only' — same contract as initLbug above; the read pool
|
||||
// must not block on a network install during query execution.
|
||||
// Windows guard: same SIGSEGV risk as doInitLbug above — skip on Windows.
|
||||
// Windows guard: same probe-then-load policy as doInitLbug above.
|
||||
if (!shared.ftsLoaded) {
|
||||
if (process.platform === 'win32') {
|
||||
shared.ftsLoaded = true;
|
||||
shared.ftsLoaded = (await hasLocalWinFtsExtension())
|
||||
? await loadFTSExtension(available[0], { policy: 'load-only' })
|
||||
: true;
|
||||
} else {
|
||||
shared.ftsLoaded = await loadFTSExtension(available[0], { policy: 'load-only' });
|
||||
}
|
||||
|
|
|
|||
|
|
@ -25,7 +25,7 @@ import {
|
|||
deleteAllCommunitiesAndProcesses,
|
||||
queryImporters,
|
||||
} from './lbug/lbug-adapter.js';
|
||||
import { createSearchFTSIndexes } from './search/fts-indexes.js';
|
||||
import { createSearchFTSIndexes, verifySearchFTSIndexes } from './search/fts-indexes.js';
|
||||
import {
|
||||
getStoragePaths,
|
||||
saveMeta,
|
||||
|
|
@ -71,6 +71,10 @@ export interface AnalyzeOptions {
|
|||
* bypass. See `allowDuplicateName` below.
|
||||
*/
|
||||
force?: boolean;
|
||||
/** Repair only search indexes without re-running full parsing/indexing. */
|
||||
repairFts?: boolean;
|
||||
/** Emit per-index FTS create logs. */
|
||||
verbose?: boolean;
|
||||
embeddings?: boolean;
|
||||
/**
|
||||
* Override the auto-skip node-count cap for embedding generation.
|
||||
|
|
@ -110,6 +114,14 @@ export interface AnalyzeOptions {
|
|||
* of a pipeline re-index.
|
||||
*/
|
||||
allowDuplicateName?: boolean;
|
||||
/**
|
||||
* Worker pool size override, threaded from the CLI `--workers` flag.
|
||||
* Forwarded to `PipelineOptions.workerPoolSize` so the parse phase
|
||||
* sizes the pool without `analyzeCommand` mutating `process.env`.
|
||||
* `0` disables the pool (sequential fallback); positive integer sets
|
||||
* the count; `undefined` defers to the env / auto-formula fallback.
|
||||
*/
|
||||
workerPoolSize?: number;
|
||||
}
|
||||
|
||||
export interface AnalyzeResult {
|
||||
|
|
@ -126,6 +138,8 @@ export interface AnalyzeResult {
|
|||
alreadyUpToDate?: boolean;
|
||||
/** The raw pipeline result — only populated when needed by callers (e.g. skill generation). */
|
||||
pipelineResult?: any;
|
||||
/** True when analyze only repaired FTS indexes and skipped pipeline re-analysis. */
|
||||
ftsRepairedOnly?: boolean;
|
||||
}
|
||||
|
||||
// Re-export the pure flag-derivation helper so external callers (and tests)
|
||||
|
|
@ -190,6 +204,78 @@ export async function runFullAnalysis(
|
|||
const currentCommit = repoHasGit ? getCurrentCommit(repoPath) : '';
|
||||
const existingMeta = await loadMeta(storagePath);
|
||||
|
||||
// ── FTS-only repair path ────────────────────────────────────────────
|
||||
if (options.repairFts) {
|
||||
if (!existingMeta) {
|
||||
throw new Error(
|
||||
'Cannot repair FTS indexes because this repository has not been analyzed yet. ' +
|
||||
'Run `gitnexus analyze` first to create the initial index, then retry `--repair-fts`.',
|
||||
);
|
||||
}
|
||||
let lbugStat;
|
||||
try {
|
||||
lbugStat = await fs.lstat(lbugPath);
|
||||
} catch {
|
||||
throw new Error(
|
||||
`Cannot repair FTS indexes: graph store at ${lbugPath} is missing. ` +
|
||||
'Run `gitnexus analyze` (full) to rebuild from scratch.',
|
||||
);
|
||||
}
|
||||
if (!lbugStat.isFile()) {
|
||||
const foundType = lbugStat.isDirectory()
|
||||
? 'a directory'
|
||||
: lbugStat.isSymbolicLink()
|
||||
? 'a symbolic link'
|
||||
: lbugStat.isSocket()
|
||||
? 'a socket'
|
||||
: lbugStat.isBlockDevice()
|
||||
? 'a block device'
|
||||
: lbugStat.isCharacterDevice()
|
||||
? 'a character device'
|
||||
: lbugStat.isFIFO()
|
||||
? 'a FIFO'
|
||||
: 'not a regular file';
|
||||
throw new Error(
|
||||
`Cannot repair FTS indexes: graph store at ${lbugPath} is ${foundType} (expected a file). ` +
|
||||
'Run `gitnexus analyze` (full) to rebuild from scratch.',
|
||||
);
|
||||
}
|
||||
try {
|
||||
await initLbug(lbugPath);
|
||||
progress('fts', 85, 'Repairing search indexes...');
|
||||
await createSearchFTSIndexes({
|
||||
onIndexStart: options.verbose
|
||||
? (table, indexName) => log(`FTS: creating ${table}.${indexName}`)
|
||||
: undefined,
|
||||
onIndexReady: options.verbose
|
||||
? (table, indexName) => log(`FTS: ready ${table}.${indexName}`)
|
||||
: undefined,
|
||||
});
|
||||
const missing = await verifySearchFTSIndexes(executeQuery);
|
||||
if (missing.length > 0) {
|
||||
throw new Error(
|
||||
`FTS repair failed - missing indexes after rebuild: ${missing.join(', ')}. ` +
|
||||
'Run `gitnexus analyze --force` to perform a full graph+FTS rebuild; ' +
|
||||
'if that also fails, verify FTS extension availability via `gitnexus doctor`.',
|
||||
);
|
||||
}
|
||||
await ensureGitNexusIgnored(repoPath);
|
||||
progress('fts', 90, 'Search indexes ready');
|
||||
progress('done', 100, 'Done');
|
||||
return {
|
||||
repoName:
|
||||
options.registryName ??
|
||||
getInferredRepoName(repoPath) ??
|
||||
path.basename(resolveRepoIdentityRoot(repoPath)),
|
||||
repoPath,
|
||||
stats: existingMeta.stats ?? {},
|
||||
ftsRepairedOnly: true,
|
||||
};
|
||||
} finally {
|
||||
await closeLbug().catch(() => {});
|
||||
}
|
||||
}
|
||||
|
||||
// ── Crash recovery: dirty flag forces full rebuild ────────────────
|
||||
// If the previous incremental run set incrementalInProgress and didn't
|
||||
// clear it, the on-disk index may be in a half-state. Cheapest path
|
||||
|
|
@ -366,7 +452,7 @@ export async function runFullAnalysis(
|
|||
: p.message || phaseLabel;
|
||||
progress(p.phase, scaled, message);
|
||||
},
|
||||
{ parseCache },
|
||||
{ parseCache, workerPoolSize: options.workerPoolSize },
|
||||
);
|
||||
|
||||
// ── Phase 2: LadybugDB (60–85%) ──────────────────────────────────
|
||||
|
|
@ -583,7 +669,21 @@ export async function runFullAnalysis(
|
|||
|
||||
// ── Phase 3: FTS (85–90%) ─────────────────────────────────────────
|
||||
progress('fts', 85, 'Creating search indexes...');
|
||||
await createSearchFTSIndexes();
|
||||
await createSearchFTSIndexes({
|
||||
onIndexStart: options.verbose
|
||||
? (table, indexName) => log(`FTS: creating ${table}.${indexName}`)
|
||||
: undefined,
|
||||
onIndexReady: options.verbose
|
||||
? (table, indexName) => log(`FTS: ready ${table}.${indexName}`)
|
||||
: undefined,
|
||||
});
|
||||
const missingIndexNames = await verifySearchFTSIndexes(executeQuery);
|
||||
if (missingIndexNames.length > 0) {
|
||||
throw new Error(
|
||||
`FTS verification failed - missing indexes after analyze: ${missingIndexNames.join(', ')}. ` +
|
||||
'Check FTS extension availability, then retry `gitnexus analyze --force` for a full rebuild.',
|
||||
);
|
||||
}
|
||||
progress('fts', 90, 'Search indexes ready');
|
||||
|
||||
// ── Phase 3.5: Re-insert cached embeddings ────────────────────────
|
||||
|
|
|
|||
|
|
@ -1,8 +1,45 @@
|
|||
import { createFTSIndex } from '../lbug/lbug-adapter.js';
|
||||
import { FTS_INDEXES } from './fts-schema.js';
|
||||
|
||||
export async function createSearchFTSIndexes(): Promise<void> {
|
||||
export interface CreateSearchFTSIndexesOptions {
|
||||
onIndexStart?: (table: string, indexName: string) => void;
|
||||
onIndexReady?: (table: string, indexName: string) => void;
|
||||
}
|
||||
|
||||
export async function createSearchFTSIndexes(
|
||||
options?: CreateSearchFTSIndexesOptions,
|
||||
): Promise<void> {
|
||||
for (const { table, indexName, properties } of FTS_INDEXES) {
|
||||
options?.onIndexStart?.(table, indexName);
|
||||
await createFTSIndex(table, indexName, [...properties]);
|
||||
options?.onIndexReady?.(table, indexName);
|
||||
}
|
||||
}
|
||||
|
||||
export async function verifySearchFTSIndexes(
|
||||
executeQuery: (cypher: string) => Promise<unknown[]>,
|
||||
): Promise<string[]> {
|
||||
const safeIdentifier = (value: string): string => {
|
||||
if (!/^[A-Za-z_][A-Za-z0-9_]*$/.test(value)) {
|
||||
throw new Error(`Invalid FTS identifier: ${value}`);
|
||||
}
|
||||
return value;
|
||||
};
|
||||
|
||||
const missing: string[] = [];
|
||||
for (const { table, indexName } of FTS_INDEXES) {
|
||||
const safeTable = safeIdentifier(table);
|
||||
const safeIndex = safeIdentifier(indexName);
|
||||
const probe = `
|
||||
CALL QUERY_FTS_INDEX('${safeTable}', '${safeIndex}', '__gitnexus_fts_probe__', conjunctive := false)
|
||||
RETURN score
|
||||
LIMIT 1
|
||||
`;
|
||||
try {
|
||||
await executeQuery(probe);
|
||||
} catch {
|
||||
missing.push(`${table}.${indexName}`);
|
||||
}
|
||||
}
|
||||
return missing;
|
||||
}
|
||||
|
|
|
|||
|
|
@ -248,6 +248,29 @@ function tryRealpath(p: string): string {
|
|||
*/
|
||||
export function resolveWorktreeCwd(repoPath: string, launchCwd: string): string {
|
||||
try {
|
||||
// Verify repoPath is a git root before comparing against its canonical
|
||||
// root. If getGitRoot returns a different path, repoPath is an arbitrary
|
||||
// subdirectory — skip both the linked-worktree guard and auto-detection
|
||||
// and fall through to the repoPath fallback.
|
||||
const repoGitRoot = getGitRoot(repoPath);
|
||||
const repoCanonical =
|
||||
repoGitRoot && tryRealpath(repoGitRoot) === tryRealpath(repoPath)
|
||||
? getCanonicalRepoRoot(repoPath)
|
||||
: null;
|
||||
|
||||
// Early exit: if repoPath is a linked worktree (differs from its canonical
|
||||
// main-checkout root), return it unchanged. Do NOT override it with the
|
||||
// server's launch directory — that would silently replace the explicitly-
|
||||
// resolved worktree index with the main checkout.
|
||||
//
|
||||
// getCanonicalRepoRoot returns the main-checkout path for both the checkout
|
||||
// and all linked worktrees:
|
||||
// repoPath === canonical → main checkout (auto-detect may fire below)
|
||||
// repoPath !== canonical → linked worktree (return as-is)
|
||||
if (repoCanonical && tryRealpath(repoPath) !== tryRealpath(repoCanonical)) {
|
||||
return repoPath;
|
||||
}
|
||||
|
||||
const launchGitRoot = getGitRoot(launchCwd);
|
||||
if (launchGitRoot) {
|
||||
// Normalise via realpathSync before comparing so macOS /var → /private/var
|
||||
|
|
@ -256,8 +279,12 @@ export function resolveWorktreeCwd(repoPath: string, launchCwd: string): string
|
|||
const realRepo = tryRealpath(repoPath);
|
||||
if (realLaunch !== realRepo) {
|
||||
const launchCanonical = getCanonicalRepoRoot(launchCwd);
|
||||
const repoCanonical = getCanonicalRepoRoot(repoPath);
|
||||
if (launchCanonical && repoCanonical && launchCanonical === repoCanonical) {
|
||||
// Use tryRealpath on both canonical values for cross-platform safety.
|
||||
if (
|
||||
launchCanonical &&
|
||||
repoCanonical &&
|
||||
tryRealpath(launchCanonical) === tryRealpath(repoCanonical)
|
||||
) {
|
||||
return launchGitRoot;
|
||||
}
|
||||
}
|
||||
|
|
@ -1039,7 +1066,7 @@ export class LocalBackend {
|
|||
timing,
|
||||
...(!ftsUsed && {
|
||||
warning:
|
||||
'FTS indexes missing — keyword search degraded. Run: gitnexus analyze --force to rebuild indexes.',
|
||||
'FTS indexes missing — keyword search degraded. Run: gitnexus analyze --repair-fts (or gitnexus analyze --force) to rebuild indexes.',
|
||||
}),
|
||||
};
|
||||
}
|
||||
|
|
|
|||
|
|
@ -448,7 +448,14 @@ export const streamGraphNdjson = async (
|
|||
*/
|
||||
const mountSSEProgress = (app: express.Express, routePath: string, jm: JobManager) => {
|
||||
app.get(routePath, (req, res) => {
|
||||
const job = jm.getJob(req.params.jobId);
|
||||
let jobId: string;
|
||||
try {
|
||||
jobId = assertString(req.params.jobId, 'jobId');
|
||||
} catch (err: any) {
|
||||
res.status(err.status ?? 400).json({ error: err.message });
|
||||
return;
|
||||
}
|
||||
const job = jm.getJob(jobId);
|
||||
if (!job) {
|
||||
res.status(404).json({ error: 'Job not found' });
|
||||
return;
|
||||
|
|
@ -494,7 +501,7 @@ const mountSSEProgress = (app: express.Express, routePath: string, jm: JobManage
|
|||
try {
|
||||
eventId++;
|
||||
if (progress.phase === 'complete' || progress.phase === 'failed') {
|
||||
const eventJob = jm.getJob(req.params.jobId);
|
||||
const eventJob = jm.getJob(jobId);
|
||||
res.write(
|
||||
`id: ${eventId}\nevent: ${progress.phase}\ndata: ${JSON.stringify({
|
||||
repoName: eventJob?.repoName,
|
||||
|
|
@ -1023,8 +1030,16 @@ export const createServer = async (port: number, host: string = '127.0.0.1') =>
|
|||
res.once('close', abortStreaming);
|
||||
|
||||
try {
|
||||
await withLbugDb(lbugPath, async () =>
|
||||
streamGraphNdjson(res, includeContent, abortController.signal),
|
||||
// Read-only open: /api/graph never writes. Write-mode opens engage
|
||||
// LadybugDB's checkpoint machinery (`.shadow` sidecar), which on
|
||||
// Windows races with the OS file handle release and trips
|
||||
// "Cannot open file ... lbug.shadow - Error 2". See pool-adapter.ts
|
||||
// which already opens read-only for the same reason, and the
|
||||
// /api/query precedent in PR #1655.
|
||||
await withLbugDb(
|
||||
lbugPath,
|
||||
async () => streamGraphNdjson(res, includeContent, abortController.signal),
|
||||
{ readOnly: true },
|
||||
);
|
||||
if (!abortController.signal.aborted && !res.writableEnded) {
|
||||
res.end();
|
||||
|
|
@ -1037,7 +1052,9 @@ export const createServer = async (port: number, host: string = '127.0.0.1') =>
|
|||
return;
|
||||
}
|
||||
|
||||
const graph = await withLbugDb(lbugPath, async () => buildGraph(includeContent));
|
||||
const graph = await withLbugDb(lbugPath, async () => buildGraph(includeContent), {
|
||||
readOnly: true,
|
||||
});
|
||||
res.json(graph);
|
||||
} catch (err: any) {
|
||||
if (err instanceof ClientDisconnectedError) {
|
||||
|
|
@ -1084,68 +1101,70 @@ export const createServer = async (port: number, host: string = '127.0.0.1') =>
|
|||
const mode: string = req.body.mode ?? 'hybrid';
|
||||
const enrich: boolean = req.body.enrich !== false; // default true
|
||||
|
||||
const results = await withLbugDb(lbugPath, async () => {
|
||||
let searchResults: any[];
|
||||
let ftsAvailable: boolean | undefined;
|
||||
const results = await withLbugDb(
|
||||
lbugPath,
|
||||
async () => {
|
||||
let searchResults: any[];
|
||||
let ftsAvailable: boolean | undefined;
|
||||
|
||||
if (mode === 'semantic') {
|
||||
const { isEmbedderReady } = await import('../core/embeddings/embedder.js');
|
||||
if (!isEmbedderReady()) {
|
||||
return { searchResults: [] as any[], ftsAvailable: undefined };
|
||||
}
|
||||
const { semanticSearch: semSearch } =
|
||||
await import('../core/embeddings/embedding-pipeline.js');
|
||||
searchResults = await semSearch(executeQuery, query, limit);
|
||||
// Normalize semantic results to HybridSearchResult shape
|
||||
searchResults = searchResults.map((r: any, i: number) => ({
|
||||
...r,
|
||||
score: r.score ?? 1 - (r.distance ?? 0),
|
||||
rank: i + 1,
|
||||
sources: ['semantic'],
|
||||
}));
|
||||
} else if (mode === 'bm25') {
|
||||
const ftsResponse = await searchFTSFromLbug(query, limit);
|
||||
ftsAvailable = ftsResponse.ftsAvailable;
|
||||
searchResults = ftsResponse.results.map((r: any, i: number) => ({
|
||||
...r,
|
||||
rank: i + 1,
|
||||
sources: ['bm25'],
|
||||
}));
|
||||
} else {
|
||||
// hybrid (default)
|
||||
const { isEmbedderReady } = await import('../core/embeddings/embedder.js');
|
||||
if (isEmbedderReady()) {
|
||||
if (mode === 'semantic') {
|
||||
const { isEmbedderReady } = await import('../core/embeddings/embedder.js');
|
||||
if (!isEmbedderReady()) {
|
||||
return { searchResults: [] as any[], ftsAvailable: undefined };
|
||||
}
|
||||
const { semanticSearch: semSearch } =
|
||||
await import('../core/embeddings/embedding-pipeline.js');
|
||||
searchResults = await hybridSearch(query, limit, executeQuery, semSearch);
|
||||
} else {
|
||||
searchResults = await semSearch(executeQuery, query, limit);
|
||||
// Normalize semantic results to HybridSearchResult shape
|
||||
searchResults = searchResults.map((r: any, i: number) => ({
|
||||
...r,
|
||||
score: r.score ?? 1 - (r.distance ?? 0),
|
||||
rank: i + 1,
|
||||
sources: ['semantic'],
|
||||
}));
|
||||
} else if (mode === 'bm25') {
|
||||
const ftsResponse = await searchFTSFromLbug(query, limit);
|
||||
ftsAvailable = ftsResponse.ftsAvailable;
|
||||
searchResults = ftsResponse.results;
|
||||
searchResults = ftsResponse.results.map((r: any, i: number) => ({
|
||||
...r,
|
||||
rank: i + 1,
|
||||
sources: ['bm25'],
|
||||
}));
|
||||
} else {
|
||||
// hybrid (default)
|
||||
const { isEmbedderReady } = await import('../core/embeddings/embedder.js');
|
||||
if (isEmbedderReady()) {
|
||||
const { semanticSearch: semSearch } =
|
||||
await import('../core/embeddings/embedding-pipeline.js');
|
||||
searchResults = await hybridSearch(query, limit, executeQuery, semSearch);
|
||||
} else {
|
||||
const ftsResponse = await searchFTSFromLbug(query, limit);
|
||||
ftsAvailable = ftsResponse.ftsAvailable;
|
||||
searchResults = ftsResponse.results;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
if (!enrich) return { searchResults, ftsAvailable };
|
||||
if (!enrich) return { searchResults, ftsAvailable };
|
||||
|
||||
// Server-side enrichment: add connections, cluster, processes per result
|
||||
// Uses parameterized queries to prevent Cypher injection via nodeId
|
||||
const validLabel = (label: string): boolean =>
|
||||
(NODE_TABLES as readonly string[]).includes(label);
|
||||
// Server-side enrichment: add connections, cluster, processes per result
|
||||
// Uses parameterized queries to prevent Cypher injection via nodeId
|
||||
const validLabel = (label: string): boolean =>
|
||||
(NODE_TABLES as readonly string[]).includes(label);
|
||||
|
||||
const enriched = await Promise.all(
|
||||
searchResults.slice(0, limit).map(async (r: any) => {
|
||||
const nodeId: string = r.nodeId || r.id || '';
|
||||
const nodeLabel = nodeId.split(':')[0];
|
||||
const enrichment: { connections?: any; cluster?: string; processes?: any[] } = {};
|
||||
const enriched = await Promise.all(
|
||||
searchResults.slice(0, limit).map(async (r: any) => {
|
||||
const nodeId: string = r.nodeId || r.id || '';
|
||||
const nodeLabel = nodeId.split(':')[0];
|
||||
const enrichment: { connections?: any; cluster?: string; processes?: any[] } = {};
|
||||
|
||||
if (!nodeId || !validLabel(nodeLabel)) return { ...r, ...enrichment };
|
||||
if (!nodeId || !validLabel(nodeLabel)) return { ...r, ...enrichment };
|
||||
|
||||
// Run connections, cluster, and process queries in parallel
|
||||
// Label is validated against NODE_TABLES (compile-time safe identifiers);
|
||||
// nodeId uses $nid parameter binding to prevent injection
|
||||
const [connRes, clusterRes, procRes] = await Promise.all([
|
||||
executePrepared(
|
||||
`
|
||||
MATCH (n:${nodeLabel} {id: $nid})
|
||||
OPTIONAL MATCH (n)-[r1:CodeRelation]->(dst)
|
||||
OPTIONAL MATCH (src)-[r2:CodeRelation]->(n)
|
||||
|
|
@ -1154,65 +1173,67 @@ export const createServer = async (port: number, host: string = '127.0.0.1') =>
|
|||
collect(DISTINCT {name: src.name, type: r2.type, confidence: r2.confidence}) AS incoming
|
||||
LIMIT 1
|
||||
`,
|
||||
{ nid: nodeId },
|
||||
).catch(() => []),
|
||||
executePrepared(
|
||||
`
|
||||
{ nid: nodeId },
|
||||
).catch(() => []),
|
||||
executePrepared(
|
||||
`
|
||||
MATCH (n:${nodeLabel} {id: $nid})
|
||||
MATCH (n)-[:CodeRelation {type: 'MEMBER_OF'}]->(c:Community)
|
||||
RETURN c.label AS label, c.description AS description
|
||||
LIMIT 1
|
||||
`,
|
||||
{ nid: nodeId },
|
||||
).catch(() => []),
|
||||
executePrepared(
|
||||
`
|
||||
{ nid: nodeId },
|
||||
).catch(() => []),
|
||||
executePrepared(
|
||||
`
|
||||
MATCH (n:${nodeLabel} {id: $nid})
|
||||
MATCH (n)-[rel:CodeRelation {type: 'STEP_IN_PROCESS'}]->(p:Process)
|
||||
RETURN p.id AS id, p.label AS label, rel.step AS step, p.stepCount AS stepCount
|
||||
ORDER BY rel.step
|
||||
`,
|
||||
{ nid: nodeId },
|
||||
).catch(() => []),
|
||||
]);
|
||||
{ nid: nodeId },
|
||||
).catch(() => []),
|
||||
]);
|
||||
|
||||
if (connRes.length > 0) {
|
||||
const row = connRes[0];
|
||||
const outgoing = (Array.isArray(row) ? row[0] : row.outgoing || [])
|
||||
.filter((c: any) => c?.name)
|
||||
.slice(0, 5);
|
||||
const incoming = (Array.isArray(row) ? row[1] : row.incoming || [])
|
||||
.filter((c: any) => c?.name)
|
||||
.slice(0, 5);
|
||||
enrichment.connections = { outgoing, incoming };
|
||||
}
|
||||
|
||||
if (clusterRes.length > 0) {
|
||||
const row = clusterRes[0];
|
||||
enrichment.cluster = Array.isArray(row) ? row[0] : row.label;
|
||||
}
|
||||
if (clusterRes.length > 0) {
|
||||
const row = clusterRes[0];
|
||||
enrichment.cluster = Array.isArray(row) ? row[0] : row.label;
|
||||
}
|
||||
|
||||
if (procRes.length > 0) {
|
||||
enrichment.processes = procRes
|
||||
.map((row: any) => ({
|
||||
id: Array.isArray(row) ? row[0] : row.id,
|
||||
label: Array.isArray(row) ? row[1] : row.label,
|
||||
step: Array.isArray(row) ? row[2] : row.step,
|
||||
stepCount: Array.isArray(row) ? row[3] : row.stepCount,
|
||||
}))
|
||||
.filter((p: any) => p.id && p.label);
|
||||
}
|
||||
|
||||
return { ...r, ...enrichment };
|
||||
}),
|
||||
);
|
||||
return { ...r, ...enrichment };
|
||||
}),
|
||||
);
|
||||
|
||||
return { searchResults: enriched, ftsAvailable };
|
||||
});
|
||||
return { searchResults: enriched, ftsAvailable };
|
||||
},
|
||||
{ readOnly: true },
|
||||
);
|
||||
const response: any = { results: results.searchResults ?? results };
|
||||
if (results.ftsAvailable === false) {
|
||||
response.warning =
|
||||
'FTS indexes missing — keyword search degraded. Run: gitnexus analyze --force to rebuild indexes.';
|
||||
'FTS indexes missing — keyword search degraded. Run: gitnexus analyze --repair-fts (or gitnexus analyze --force) to rebuild indexes.';
|
||||
}
|
||||
res.json(response);
|
||||
} catch (err: any) {
|
||||
|
|
@ -1288,8 +1309,11 @@ export const createServer = async (port: number, host: string = '127.0.0.1') =>
|
|||
|
||||
// Get file paths from the graph (lightweight — no content loaded)
|
||||
const lbugPath = path.join(entry.storagePath, 'lbug');
|
||||
const fileRows = await withLbugDb(lbugPath, () =>
|
||||
executeQuery(`MATCH (n:File) WHERE n.content IS NOT NULL RETURN n.filePath AS filePath`),
|
||||
const fileRows = await withLbugDb(
|
||||
lbugPath,
|
||||
() =>
|
||||
executeQuery(`MATCH (n:File) WHERE n.content IS NOT NULL RETURN n.filePath AS filePath`),
|
||||
{ readOnly: true },
|
||||
);
|
||||
|
||||
// Search files on disk one at a time (constant memory)
|
||||
|
|
|
|||
|
|
@ -2,6 +2,7 @@ export class User {
|
|||
save() {}
|
||||
}
|
||||
|
||||
/** @returns {User} */
|
||||
export function getUser() {
|
||||
return new User();
|
||||
}
|
||||
|
|
|
|||
|
|
@ -3,6 +3,7 @@ export class User {
|
|||
getName() { return ''; }
|
||||
}
|
||||
|
||||
/** @returns {User} */
|
||||
export function getUser() {
|
||||
return new User();
|
||||
}
|
||||
|
|
|
|||
12
gitnexus/test/fixtures/lang-resolution/cpp-overload-pointer-null-ellipsis/lib.cpp
vendored
Normal file
12
gitnexus/test/fixtures/lang-resolution/cpp-overload-pointer-null-ellipsis/lib.cpp
vendored
Normal file
|
|
@ -0,0 +1,12 @@
|
|||
#include "lib.h"
|
||||
|
||||
void Service::f(int* p) {}
|
||||
void Service::f(bool flag) {}
|
||||
|
||||
void Service::g(int a, int b) {}
|
||||
void Service::g(int a, ...) {}
|
||||
|
||||
void Service::h(int a, double b) {}
|
||||
void Service::h(int a, ...) {}
|
||||
|
||||
void Service::k(int a, ...) {}
|
||||
38
gitnexus/test/fixtures/lang-resolution/cpp-overload-pointer-null-ellipsis/lib.h
vendored
Normal file
38
gitnexus/test/fixtures/lang-resolution/cpp-overload-pointer-null-ellipsis/lib.h
vendored
Normal file
|
|
@ -0,0 +1,38 @@
|
|||
#pragma once
|
||||
|
||||
class Service {
|
||||
public:
|
||||
void f(int* p);
|
||||
void f(bool flag);
|
||||
|
||||
void g(int a, int b);
|
||||
void g(int a, ...);
|
||||
|
||||
void h(int a, double b);
|
||||
void h(int a, ...);
|
||||
|
||||
void k(int a, ...);
|
||||
|
||||
void runNullptr() {
|
||||
f(nullptr);
|
||||
}
|
||||
|
||||
void runPointer() {
|
||||
int* p = nullptr;
|
||||
f(p);
|
||||
}
|
||||
|
||||
void runBoolConversion() {
|
||||
f(42);
|
||||
}
|
||||
|
||||
void run() {
|
||||
int* p = nullptr;
|
||||
f(nullptr);
|
||||
f(p);
|
||||
f(42);
|
||||
g(1, 2);
|
||||
h(1, 'a');
|
||||
k(1, 2, 3);
|
||||
}
|
||||
};
|
||||
16
gitnexus/test/fixtures/lang-resolution/cpp-sfinae-is-class/main.cpp
vendored
Normal file
16
gitnexus/test/fixtures/lang-resolution/cpp-sfinae-is-class/main.cpp
vendored
Normal file
|
|
@ -0,0 +1,16 @@
|
|||
#include <type_traits>
|
||||
|
||||
struct S {};
|
||||
|
||||
template <class T, std::enable_if_t<std::is_class_v<T>, int> = 0>
|
||||
void pick(T value) {}
|
||||
|
||||
template <class T, std::enable_if_t<std::is_integral_v<T>, int> = 0>
|
||||
void pick(T value) {}
|
||||
|
||||
void run() {
|
||||
S s;
|
||||
int n = 0;
|
||||
pick(s);
|
||||
pick(n);
|
||||
}
|
||||
14
gitnexus/test/fixtures/lang-resolution/cpp-sfinae-is-const-volatile/main.cpp
vendored
Normal file
14
gitnexus/test/fixtures/lang-resolution/cpp-sfinae-is-const-volatile/main.cpp
vendored
Normal file
|
|
@ -0,0 +1,14 @@
|
|||
#include <type_traits>
|
||||
|
||||
template <class T, std::enable_if_t<std::is_const_v<T>, int> = 0>
|
||||
void pick(T value) {}
|
||||
|
||||
template <class T, std::enable_if_t<std::is_volatile_v<T>, int> = 0>
|
||||
void pick(T value) {}
|
||||
|
||||
void run() {
|
||||
const int c = 0;
|
||||
volatile int v = 0;
|
||||
pick(c);
|
||||
pick(v);
|
||||
}
|
||||
16
gitnexus/test/fixtures/lang-resolution/cpp-sfinae-is-enum/main.cpp
vendored
Normal file
16
gitnexus/test/fixtures/lang-resolution/cpp-sfinae-is-enum/main.cpp
vendored
Normal file
|
|
@ -0,0 +1,16 @@
|
|||
#include <type_traits>
|
||||
|
||||
enum Color { Red };
|
||||
|
||||
template <class T, std::enable_if_t<std::is_enum_v<T>, int> = 0>
|
||||
void pick(T value) {}
|
||||
|
||||
template <class T, std::enable_if_t<std::is_integral_v<T>, int> = 0>
|
||||
void pick(T value) {}
|
||||
|
||||
void run() {
|
||||
Color color = Red;
|
||||
int n = 0;
|
||||
pick(color);
|
||||
pick(n);
|
||||
}
|
||||
14
gitnexus/test/fixtures/lang-resolution/cpp-sfinae-is-pointer/main.cpp
vendored
Normal file
14
gitnexus/test/fixtures/lang-resolution/cpp-sfinae-is-pointer/main.cpp
vendored
Normal file
|
|
@ -0,0 +1,14 @@
|
|||
#include <type_traits>
|
||||
|
||||
struct S {};
|
||||
|
||||
template <class T, std::enable_if_t<std::is_pointer_v<T>, int> = 0>
|
||||
void pick(T value) {}
|
||||
|
||||
template <class T, std::enable_if_t<std::is_class_v<T>, int> = 0>
|
||||
void pick(T value) {}
|
||||
|
||||
void run(S* p, S s) {
|
||||
pick(p);
|
||||
pick(s);
|
||||
}
|
||||
14
gitnexus/test/fixtures/lang-resolution/cpp-sfinae-is-reference/main.cpp
vendored
Normal file
14
gitnexus/test/fixtures/lang-resolution/cpp-sfinae-is-reference/main.cpp
vendored
Normal file
|
|
@ -0,0 +1,14 @@
|
|||
#include <type_traits>
|
||||
|
||||
template <class T, std::enable_if_t<std::is_reference_v<T>, int> = 0>
|
||||
void pick(T value) {}
|
||||
|
||||
template <class T, std::enable_if_t<std::is_integral_v<T>, int> = 0>
|
||||
void pick(T value) {}
|
||||
|
||||
void run() {
|
||||
int n = 0;
|
||||
int& r = n;
|
||||
pick(r);
|
||||
pick(n);
|
||||
}
|
||||
12
gitnexus/test/fixtures/lang-resolution/cpp-sfinae-is-void/main.cpp
vendored
Normal file
12
gitnexus/test/fixtures/lang-resolution/cpp-sfinae-is-void/main.cpp
vendored
Normal file
|
|
@ -0,0 +1,12 @@
|
|||
#include <type_traits>
|
||||
|
||||
template <class T, std::enable_if_t<std::is_void_v<T>, int> = 0>
|
||||
void pick(T value) {}
|
||||
|
||||
template <class T, std::enable_if_t<std::is_pointer_v<T>, int> = 0>
|
||||
void pick(T value) {}
|
||||
|
||||
void run() {
|
||||
void* p;
|
||||
pick(p);
|
||||
}
|
||||
|
|
@ -0,0 +1,8 @@
|
|||
package com.example;
|
||||
|
||||
public class Module1App {
|
||||
public void run() {
|
||||
UserService service = new UserService();
|
||||
service.ping();
|
||||
}
|
||||
}
|
||||
|
|
@ -0,0 +1,6 @@
|
|||
package com.example;
|
||||
|
||||
public class UserService {
|
||||
public void ping() {
|
||||
}
|
||||
}
|
||||
|
|
@ -0,0 +1,8 @@
|
|||
package com.example;
|
||||
|
||||
public class Module2App {
|
||||
public void run() {
|
||||
UserService service = new UserService();
|
||||
service.ping();
|
||||
}
|
||||
}
|
||||
|
|
@ -0,0 +1,6 @@
|
|||
package com.example;
|
||||
|
||||
public class UserService {
|
||||
public void ping() {
|
||||
}
|
||||
}
|
||||
|
|
@ -4,7 +4,8 @@
|
|||
* Creates temporary directories for tests and provides cleanup that tolerates
|
||||
* LadybugDB's known Windows handle-release lag after retries.
|
||||
*/
|
||||
import fs from 'fs/promises';
|
||||
import fs from 'fs';
|
||||
import fsp from 'fs/promises';
|
||||
import os from 'os';
|
||||
import path from 'path';
|
||||
|
||||
|
|
@ -13,22 +14,56 @@ export interface TestDBHandle {
|
|||
cleanup: () => Promise<void>;
|
||||
}
|
||||
|
||||
const CLEANUP_MAX_ATTEMPTS = 5;
|
||||
const WINDOWS_NATIVE_LOCK_CODES = new Set(['EBUSY', 'EPERM', 'EACCES', 'ENOTEMPTY']);
|
||||
|
||||
export async function cleanupTempDir(tmpDir: string): Promise<void> {
|
||||
const cleanupBackoffMs = (attempt: number): number => 100 * (attempt + 1);
|
||||
|
||||
const shouldSwallowCleanupError = (err: unknown): boolean => {
|
||||
const code = (err as NodeJS.ErrnoException | undefined)?.code;
|
||||
return process.platform === 'win32' && WINDOWS_NATIVE_LOCK_CODES.has(code ?? '');
|
||||
};
|
||||
|
||||
const sleepSync = (ms: number): void => {
|
||||
const view = new Int32Array(new SharedArrayBuffer(4));
|
||||
Atomics.wait(view, 0, 0, ms);
|
||||
};
|
||||
|
||||
export function cleanupTempDirSync(tmpDir: string): void {
|
||||
let lastError: unknown;
|
||||
for (let attempt = 0; attempt < 5; attempt++) {
|
||||
for (let attempt = 0; attempt < CLEANUP_MAX_ATTEMPTS; attempt++) {
|
||||
try {
|
||||
await fs.rm(tmpDir, { recursive: true, force: true });
|
||||
fs.rmSync(tmpDir, { recursive: true, force: true });
|
||||
return;
|
||||
} catch (err) {
|
||||
lastError = err;
|
||||
await new Promise((resolve) => setTimeout(resolve, 100 * (attempt + 1)));
|
||||
if (attempt < CLEANUP_MAX_ATTEMPTS - 1) {
|
||||
sleepSync(cleanupBackoffMs(attempt));
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
const code = (lastError as NodeJS.ErrnoException | undefined)?.code;
|
||||
if (process.platform === 'win32' && WINDOWS_NATIVE_LOCK_CODES.has(code ?? '')) {
|
||||
if (shouldSwallowCleanupError(lastError)) {
|
||||
return;
|
||||
}
|
||||
throw lastError;
|
||||
}
|
||||
|
||||
export async function cleanupTempDir(tmpDir: string): Promise<void> {
|
||||
let lastError: unknown;
|
||||
for (let attempt = 0; attempt < CLEANUP_MAX_ATTEMPTS; attempt++) {
|
||||
try {
|
||||
await fsp.rm(tmpDir, { recursive: true, force: true });
|
||||
return;
|
||||
} catch (err) {
|
||||
lastError = err;
|
||||
if (attempt < CLEANUP_MAX_ATTEMPTS - 1) {
|
||||
await new Promise((resolve) => setTimeout(resolve, cleanupBackoffMs(attempt)));
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
if (shouldSwallowCleanupError(lastError)) {
|
||||
return;
|
||||
}
|
||||
throw lastError;
|
||||
|
|
@ -46,7 +81,7 @@ export async function cleanupTempDir(tmpDir: string): Promise<void> {
|
|||
* return.
|
||||
*/
|
||||
export async function createTempDir(prefix: string = 'gitnexus-test-'): Promise<TestDBHandle> {
|
||||
const tmpDir = await fs.mkdtemp(path.join(os.tmpdir(), prefix));
|
||||
const tmpDir = await fsp.mkdtemp(path.join(os.tmpdir(), prefix));
|
||||
return {
|
||||
dbPath: tmpDir,
|
||||
cleanup: async () => {
|
||||
|
|
|
|||
|
|
@ -16,6 +16,7 @@ import os from 'os';
|
|||
import { fileURLToPath, pathToFileURL } from 'url';
|
||||
|
||||
import { createRequire } from 'module';
|
||||
import { cleanupTempDirSync } from '../helpers/test-db.js';
|
||||
|
||||
const testDir = path.dirname(fileURLToPath(import.meta.url));
|
||||
const repoRoot = path.resolve(testDir, '../..');
|
||||
|
|
@ -75,10 +76,10 @@ afterAll(() => {
|
|||
// Entire tmp copy goes away — no selective cleanup needed. The shared
|
||||
// `test/fixtures/mini-repo/` source was never touched.
|
||||
if (tmpParent) {
|
||||
fs.rmSync(tmpParent, { recursive: true, force: true });
|
||||
cleanupTempDirSync(tmpParent);
|
||||
}
|
||||
if (suiteGitnexusHome) {
|
||||
fs.rmSync(suiteGitnexusHome, { recursive: true, force: true });
|
||||
cleanupTempDirSync(suiteGitnexusHome);
|
||||
}
|
||||
});
|
||||
|
||||
|
|
@ -268,8 +269,8 @@ describe('CLI end-to-end', () => {
|
|||
`registry has no entry for ${repo}; entries: ${JSON.stringify(entries.map((e) => e.path))}`,
|
||||
).toBe(true);
|
||||
} finally {
|
||||
fs.rmSync(gnHome, { recursive: true, force: true });
|
||||
fs.rmSync(repoParent, { recursive: true, force: true });
|
||||
cleanupTempDirSync(gnHome);
|
||||
cleanupTempDirSync(repoParent);
|
||||
}
|
||||
}, 60_000);
|
||||
|
||||
|
|
@ -310,8 +311,8 @@ describe('CLI end-to-end', () => {
|
|||
expect(`${second.stdout}${second.stderr}`).toMatch(/registry entry/i);
|
||||
expect(second.status).toBe(1);
|
||||
} finally {
|
||||
fs.rmSync(gnHome, { recursive: true, force: true });
|
||||
fs.rmSync(repoParent, { recursive: true, force: true });
|
||||
cleanupTempDirSync(gnHome);
|
||||
cleanupTempDirSync(repoParent);
|
||||
}
|
||||
}, 60_000);
|
||||
|
||||
|
|
@ -457,12 +458,12 @@ describe('CLI end-to-end', () => {
|
|||
const afterStep4 = JSON.parse(fs.readFileSync(registryPath, 'utf-8'));
|
||||
expect(afterStep4).toHaveLength(2);
|
||||
} finally {
|
||||
fs.rmSync(parentC, { recursive: true, force: true });
|
||||
cleanupTempDirSync(parentC);
|
||||
}
|
||||
} finally {
|
||||
fs.rmSync(gnHome, { recursive: true, force: true });
|
||||
fs.rmSync(parentA, { recursive: true, force: true });
|
||||
fs.rmSync(parentB, { recursive: true, force: true });
|
||||
cleanupTempDirSync(gnHome);
|
||||
cleanupTempDirSync(parentA);
|
||||
cleanupTempDirSync(parentB);
|
||||
}
|
||||
}, 360000); // 6-min outer budget (4 × ~60s analyze calls + fixture setup)
|
||||
});
|
||||
|
|
@ -571,8 +572,8 @@ describe('CLI end-to-end', () => {
|
|||
expect(r4.status).toBe(0);
|
||||
expect(`${r4.stdout}${r4.stderr}`).toMatch(/Nothing to remove/i);
|
||||
} finally {
|
||||
fs.rmSync(gnHome, { recursive: true, force: true });
|
||||
fs.rmSync(parentA, { recursive: true, force: true });
|
||||
cleanupTempDirSync(gnHome);
|
||||
cleanupTempDirSync(parentA);
|
||||
}
|
||||
}, 180000); // 3-min outer budget (1 × ~60s analyze + 3 × fast remove calls)
|
||||
|
||||
|
|
@ -675,9 +676,9 @@ describe('CLI end-to-end', () => {
|
|||
// And it's NOT the one we just removed.
|
||||
expect(finalEntries[0].path).not.toBe(repoAEntry.path);
|
||||
} finally {
|
||||
fs.rmSync(gnHome, { recursive: true, force: true });
|
||||
fs.rmSync(parentA, { recursive: true, force: true });
|
||||
fs.rmSync(parentB, { recursive: true, force: true });
|
||||
cleanupTempDirSync(gnHome);
|
||||
cleanupTempDirSync(parentA);
|
||||
cleanupTempDirSync(parentB);
|
||||
}
|
||||
}, 240000); // 4-min outer budget (2 × ~60s analyze + 2 × fast remove)
|
||||
|
||||
|
|
@ -759,8 +760,8 @@ describe('CLI end-to-end', () => {
|
|||
expect(afterRegistry).toHaveLength(1);
|
||||
expect(afterRegistry[0].storagePath).toBe(repo); // still poisoned (we did that)
|
||||
} finally {
|
||||
fs.rmSync(gnHome, { recursive: true, force: true });
|
||||
fs.rmSync(parent, { recursive: true, force: true });
|
||||
cleanupTempDirSync(gnHome);
|
||||
cleanupTempDirSync(parent);
|
||||
}
|
||||
}, 120000); // 2-min budget (1 × ~60s analyze + 1 × fast remove-refused)
|
||||
});
|
||||
|
|
@ -864,9 +865,9 @@ describe('CLI end-to-end', () => {
|
|||
expect(afterRegistry).toHaveLength(1);
|
||||
expect(afterRegistry[0].name).toBe('bad-alias');
|
||||
} finally {
|
||||
fs.rmSync(gnHome, { recursive: true, force: true });
|
||||
fs.rmSync(parentBad, { recursive: true, force: true });
|
||||
fs.rmSync(parentGood, { recursive: true, force: true });
|
||||
cleanupTempDirSync(gnHome);
|
||||
cleanupTempDirSync(parentBad);
|
||||
cleanupTempDirSync(parentGood);
|
||||
}
|
||||
}, 240000); // 4-min budget (2 × ~60s analyze + 1 × fast clean --all)
|
||||
});
|
||||
|
|
@ -954,7 +955,7 @@ describe('CLI end-to-end', () => {
|
|||
expect(result.status).toBe(0);
|
||||
expect(result.stdout).toMatch(/Repository not indexed/);
|
||||
} finally {
|
||||
fs.rmSync(tmpDir, { recursive: true, force: true });
|
||||
cleanupTempDirSync(tmpDir);
|
||||
}
|
||||
});
|
||||
|
||||
|
|
@ -968,7 +969,7 @@ describe('CLI end-to-end', () => {
|
|||
expect(result.status).toBe(0);
|
||||
expect(result.stdout).toMatch(/Not a git repository/);
|
||||
} finally {
|
||||
fs.rmSync(tmpDir, { recursive: true, force: true });
|
||||
cleanupTempDirSync(tmpDir);
|
||||
}
|
||||
});
|
||||
|
||||
|
|
@ -984,7 +985,7 @@ describe('CLI end-to-end', () => {
|
|||
expect(result.status).toBe(1);
|
||||
expect(result.stdout).toMatch(/not.*git repository/i);
|
||||
} finally {
|
||||
fs.rmSync(tmpDir, { recursive: true, force: true });
|
||||
cleanupTempDirSync(tmpDir);
|
||||
}
|
||||
});
|
||||
});
|
||||
|
|
@ -1014,7 +1015,7 @@ describe('CLI end-to-end', () => {
|
|||
expect(result.status).toBe(1);
|
||||
expect(result.stdout).toMatch(/not.*git repository/i);
|
||||
} finally {
|
||||
fs.rmSync(tmpDir, { recursive: true, force: true });
|
||||
cleanupTempDirSync(tmpDir);
|
||||
}
|
||||
});
|
||||
|
||||
|
|
@ -1051,7 +1052,7 @@ describe('CLI end-to-end', () => {
|
|||
expect(result.status).toBe(1);
|
||||
expect(result.stdout).toMatch(/No GitNexus index found/);
|
||||
} finally {
|
||||
fs.rmSync(tmpDir, { recursive: true, force: true });
|
||||
cleanupTempDirSync(tmpDir);
|
||||
}
|
||||
});
|
||||
|
||||
|
|
@ -1407,5 +1408,102 @@ describe('CLI end-to-end', () => {
|
|||
}, 30000);
|
||||
});
|
||||
}, 35000);
|
||||
|
||||
it('emits READY signal with bound IP (not literal "localhost") when --host localhost is used', () => {
|
||||
return new Promise<void>((resolve, reject) => {
|
||||
const child = spawn(
|
||||
process.execPath,
|
||||
[
|
||||
'--import',
|
||||
tsxImportUrl,
|
||||
cliEntry,
|
||||
'eval-server',
|
||||
'--port',
|
||||
'0',
|
||||
'--host',
|
||||
'localhost',
|
||||
'--idle-timeout',
|
||||
'3',
|
||||
],
|
||||
{
|
||||
cwd: MINI_REPO,
|
||||
stdio: ['ignore', 'pipe', 'pipe'],
|
||||
env: cliEnv(),
|
||||
},
|
||||
);
|
||||
|
||||
let stdoutBuffer = '';
|
||||
let settled = false;
|
||||
|
||||
const settle = (fn: () => void) => {
|
||||
if (settled) return;
|
||||
settled = true;
|
||||
clearTimeout(timer);
|
||||
child.kill('SIGTERM');
|
||||
fn();
|
||||
};
|
||||
|
||||
child.stdout.on('data', async (chunk: Buffer) => {
|
||||
stdoutBuffer += chunk.toString();
|
||||
const readyLine = stdoutBuffer
|
||||
.split('\n')
|
||||
.find((l) => l.startsWith('GITNEXUS_EVAL_SERVER_READY:'));
|
||||
if (!readyLine || settled) return;
|
||||
|
||||
// The signal must contain a real bound IP, not the literal input string
|
||||
if (readyLine.includes(':localhost:')) {
|
||||
settle(() =>
|
||||
reject(
|
||||
new Error(
|
||||
`READY signal contained literal "localhost" instead of a bound IP:\n${readyLine}`,
|
||||
),
|
||||
),
|
||||
);
|
||||
return;
|
||||
}
|
||||
|
||||
// Parse host and port: everything after the prefix up to the last colon
|
||||
const withoutPrefix = readyLine.slice('GITNEXUS_EVAL_SERVER_READY:'.length);
|
||||
const lastColon = withoutPrefix.lastIndexOf(':');
|
||||
const signalHost = withoutPrefix.slice(0, lastColon); // "127.0.0.1" or "[::1]"
|
||||
const boundPort = withoutPrefix.slice(lastColon + 1).trim();
|
||||
if (!boundPort || isNaN(Number(boundPort))) {
|
||||
settle(() => reject(new Error(`Could not parse port from READY signal: ${readyLine}`)));
|
||||
return;
|
||||
}
|
||||
|
||||
// Probe /health at the bound address to confirm the server is reachable
|
||||
try {
|
||||
const res = await fetch(`http://${signalHost}:${boundPort}/health`);
|
||||
if (res.status === 200) {
|
||||
settle(resolve);
|
||||
} else {
|
||||
settle(() => reject(new Error(`/health returned ${res.status}, expected 200`)));
|
||||
}
|
||||
} catch (err) {
|
||||
settle(() =>
|
||||
reject(
|
||||
new Error(
|
||||
`eval-server bound to localhost but /health unreachable at ${signalHost}:${boundPort}: ${err}`,
|
||||
),
|
||||
),
|
||||
);
|
||||
}
|
||||
});
|
||||
|
||||
child.stderr.on('data', (chunk: Buffer) => {
|
||||
const text = chunk.toString();
|
||||
if (text.includes('unknown option') || text.includes('error: unknown')) {
|
||||
settle(() => reject(new Error(`eval-server rejected --host flag:\n${text}`)));
|
||||
}
|
||||
});
|
||||
|
||||
const timer = setTimeout(() => {
|
||||
settle(() =>
|
||||
reject(new Error('eval-server --host localhost did not emit READY signal within 30s')),
|
||||
);
|
||||
}, 30000);
|
||||
});
|
||||
}, 35000);
|
||||
});
|
||||
});
|
||||
|
|
|
|||
|
|
@ -398,5 +398,172 @@ describe('filesystem-walker', () => {
|
|||
expect(skipWarnings.length).toBeGreaterThan(0);
|
||||
expect(String(skipWarnings[0].msg ?? '')).toContain('generated/vendored');
|
||||
});
|
||||
|
||||
// Regression: issue #1659. The skipped-paths list and the
|
||||
// GITNEXUS_MAX_FILE_SIZE hint must appear by default, otherwise users
|
||||
// see "Skipped N large files" with no actionable detail and misdiagnose
|
||||
// missing IMPORTS/CALLS edges as a resolver bug.
|
||||
it('lists the skipped path by default (not gated behind GITNEXUS_VERBOSE)', async () => {
|
||||
await walkRepositoryPaths(sizeDir);
|
||||
const pathWarnings = cap.records().filter((r) => String(r.msg ?? '').includes(BIG_FILE));
|
||||
expect(pathWarnings.length).toBeGreaterThan(0);
|
||||
});
|
||||
|
||||
it('emits a GITNEXUS_MAX_FILE_SIZE hint when running with the default cap', async () => {
|
||||
await walkRepositoryPaths(sizeDir);
|
||||
const hint = cap
|
||||
.records()
|
||||
.filter((r) => String(r.msg ?? '').includes('GITNEXUS_MAX_FILE_SIZE=<KB>'));
|
||||
expect(hint.length).toBe(1);
|
||||
});
|
||||
|
||||
it('omits the GITNEXUS_MAX_FILE_SIZE hint when an override is active', async () => {
|
||||
process.env.GITNEXUS_MAX_FILE_SIZE = '1';
|
||||
await walkRepositoryPaths(sizeDir);
|
||||
const hint = cap
|
||||
.records()
|
||||
.filter((r) => String(r.msg ?? '').includes('GITNEXUS_MAX_FILE_SIZE=<KB>'));
|
||||
expect(hint.length).toBe(0);
|
||||
});
|
||||
|
||||
// Edge case from the #1661 adversarial review: setting GITNEXUS_MAX_FILE_SIZE
|
||||
// to the same value as the default (512KB) used to still print the hint
|
||||
// because the byte comparison resolved to equal. The hint should care
|
||||
// about whether the operator set the env var, not what value they chose.
|
||||
it('omits the GITNEXUS_MAX_FILE_SIZE hint when the override equals the default value', async () => {
|
||||
process.env.GITNEXUS_MAX_FILE_SIZE = '512';
|
||||
await walkRepositoryPaths(sizeDir);
|
||||
const hint = cap
|
||||
.records()
|
||||
.filter((r) => String(r.msg ?? '').includes('GITNEXUS_MAX_FILE_SIZE=<KB>'));
|
||||
expect(hint.length).toBe(0);
|
||||
});
|
||||
});
|
||||
|
||||
describe('large file skip preview cap (#1659)', () => {
|
||||
let manyDir: string;
|
||||
const ORIGINAL_ENV = process.env.GITNEXUS_MAX_FILE_SIZE;
|
||||
const ORIGINAL_VERBOSE = process.env.GITNEXUS_VERBOSE;
|
||||
let cap: ReturnType<typeof _captureLogger>;
|
||||
|
||||
beforeAll(async () => {
|
||||
manyDir = await fs.mkdtemp(path.join(os.tmpdir(), 'gn-walker-size-many-'));
|
||||
await fs.mkdir(path.join(manyDir, 'src'), { recursive: true });
|
||||
// 8 files >512KB so the preview-cap path (5) is exercised.
|
||||
for (let i = 0; i < 8; i++) {
|
||||
await fs.writeFile(path.join(manyDir, 'src', `big${i}.ts`), 'x'.repeat(600 * 1024));
|
||||
}
|
||||
});
|
||||
|
||||
afterAll(async () => {
|
||||
await fs.rm(manyDir, { recursive: true, force: true });
|
||||
});
|
||||
|
||||
beforeEach(() => {
|
||||
delete process.env.GITNEXUS_MAX_FILE_SIZE;
|
||||
delete process.env.GITNEXUS_VERBOSE;
|
||||
_resetMaxFileSizeWarnings();
|
||||
cap = _captureLogger();
|
||||
});
|
||||
|
||||
afterEach(() => {
|
||||
if (ORIGINAL_ENV === undefined) {
|
||||
delete process.env.GITNEXUS_MAX_FILE_SIZE;
|
||||
} else {
|
||||
process.env.GITNEXUS_MAX_FILE_SIZE = ORIGINAL_ENV;
|
||||
}
|
||||
if (ORIGINAL_VERBOSE === undefined) {
|
||||
delete process.env.GITNEXUS_VERBOSE;
|
||||
} else {
|
||||
process.env.GITNEXUS_VERBOSE = ORIGINAL_VERBOSE;
|
||||
}
|
||||
cap.restore();
|
||||
});
|
||||
|
||||
it('truncates the path list to 5 and mentions GITNEXUS_VERBOSE when over the cap', async () => {
|
||||
await walkRepositoryPaths(manyDir);
|
||||
const pathLines = cap.records().filter((r) => /^\s*-\s/.test(String(r.msg ?? '')));
|
||||
expect(pathLines.length).toBe(5);
|
||||
const more = cap
|
||||
.records()
|
||||
.filter((r) => String(r.msg ?? '').includes('and 3 more (set GITNEXUS_VERBOSE=1'));
|
||||
expect(more.length).toBe(1);
|
||||
});
|
||||
|
||||
// Boundary check from the #1661 adversarial review: the SKIPPED_PREVIEW_CAP
|
||||
// comparison is `<=`, so 5 paths should list all five without a truncation
|
||||
// line and 6 paths should list exactly five plus "...and 1 more". Tested
|
||||
// explicitly so a future off-by-one refactor (`<=` → `<`) fails fast.
|
||||
it('lists all paths and omits the truncation line at exactly 5 skipped files', async () => {
|
||||
const fiveDir = await fs.mkdtemp(path.join(os.tmpdir(), 'gn-walker-size-five-'));
|
||||
try {
|
||||
await fs.mkdir(path.join(fiveDir, 'src'), { recursive: true });
|
||||
for (let i = 0; i < 5; i++) {
|
||||
await fs.writeFile(path.join(fiveDir, 'src', `big${i}.ts`), 'x'.repeat(600 * 1024));
|
||||
}
|
||||
await walkRepositoryPaths(fiveDir);
|
||||
const pathLines = cap.records().filter((r) => /^\s*-\s/.test(String(r.msg ?? '')));
|
||||
expect(pathLines.length).toBe(5);
|
||||
const more = cap.records().filter((r) => String(r.msg ?? '').includes('...and '));
|
||||
expect(more.length).toBe(0);
|
||||
} finally {
|
||||
await fs.rm(fiveDir, { recursive: true, force: true });
|
||||
}
|
||||
});
|
||||
|
||||
it('lists exactly 5 paths plus "...and 1 more" at exactly 6 skipped files', async () => {
|
||||
const sixDir = await fs.mkdtemp(path.join(os.tmpdir(), 'gn-walker-size-six-'));
|
||||
try {
|
||||
await fs.mkdir(path.join(sixDir, 'src'), { recursive: true });
|
||||
for (let i = 0; i < 6; i++) {
|
||||
await fs.writeFile(path.join(sixDir, 'src', `big${i}.ts`), 'x'.repeat(600 * 1024));
|
||||
}
|
||||
await walkRepositoryPaths(sixDir);
|
||||
const pathLines = cap.records().filter((r) => /^\s*-\s/.test(String(r.msg ?? '')));
|
||||
expect(pathLines.length).toBe(5);
|
||||
const more = cap
|
||||
.records()
|
||||
.filter((r) => String(r.msg ?? '').includes('and 1 more (set GITNEXUS_VERBOSE=1'));
|
||||
expect(more.length).toBe(1);
|
||||
} finally {
|
||||
await fs.rm(sixDir, { recursive: true, force: true });
|
||||
}
|
||||
});
|
||||
|
||||
it('lists every skipped path when GITNEXUS_VERBOSE=1', async () => {
|
||||
process.env.GITNEXUS_VERBOSE = '1';
|
||||
await walkRepositoryPaths(manyDir);
|
||||
const pathLines = cap.records().filter((r) => /^\s*-\s/.test(String(r.msg ?? '')));
|
||||
expect(pathLines.length).toBe(8);
|
||||
const more = cap.records().filter((r) => String(r.msg ?? '').includes('and '));
|
||||
expect(more.length).toBe(0);
|
||||
});
|
||||
|
||||
// Issue #1659 follow-up (PR #1661 review): paths were pushed in fs.stat
|
||||
// completion order, so the default preview could vary between runs on
|
||||
// the same repo. The implementation sorts skippedLargePaths before
|
||||
// slicing, so the listed paths come out in sorted order, which is the
|
||||
// stable contract operators can rely on.
|
||||
it('lists skipped paths in sorted order (deterministic preview)', async () => {
|
||||
process.env.GITNEXUS_VERBOSE = '1';
|
||||
await walkRepositoryPaths(manyDir);
|
||||
const pathLines = cap
|
||||
.records()
|
||||
.map((r) => String(r.msg ?? ''))
|
||||
.filter((m) => /^\s*-\s/.test(m))
|
||||
.map((m) => m.replace(/^\s*-\s*/, ''));
|
||||
expect(pathLines).toEqual([...pathLines].sort());
|
||||
// sanity-check we actually saw all 8 of the manyDir fixture
|
||||
expect(pathLines).toEqual([
|
||||
'src/big0.ts',
|
||||
'src/big1.ts',
|
||||
'src/big2.ts',
|
||||
'src/big3.ts',
|
||||
'src/big4.ts',
|
||||
'src/big5.ts',
|
||||
'src/big6.ts',
|
||||
'src/big7.ts',
|
||||
]);
|
||||
});
|
||||
});
|
||||
});
|
||||
|
|
|
|||
177
gitnexus/test/integration/parse-impl-large-fixture.test.ts
Normal file
177
gitnexus/test/integration/parse-impl-large-fixture.test.ts
Normal file
|
|
@ -0,0 +1,177 @@
|
|||
/**
|
||||
* U6 (B3 from PR #1693 review) — Multi-chunk pipeline integration with a
|
||||
* wall-clock budget.
|
||||
*
|
||||
* The PR's headline claim is "analyze no longer hangs on TS-root-shaped
|
||||
* loads". The unit suite already pins each resilience layer individually
|
||||
* (worker-pool-resilience.test.ts), the deferred-extraction equivalence
|
||||
* (parse-impl-deferred-extraction.test.ts — U7), and the chunk
|
||||
* concurrency (parse-impl-chunk-concurrency.test.ts — U1). What was
|
||||
* missing: a single end-to-end run that exercises the full chunked
|
||||
* parse-and-resolve path on a multi-chunk fixture, BOUNDED by a
|
||||
* wall-clock so a regression that re-introduces the hang fails this
|
||||
* test loudly instead of slipping past via inequality assertions.
|
||||
*
|
||||
* Scope note: this test runs the sequential-fallback path (skipWorkers).
|
||||
* The full "real workers + actually-pathological file" scenario from
|
||||
* the plan requires a built `dist/parse-worker.js` and ~60s wall-clock
|
||||
* per run, which is more appropriate for a CI-integration job than a
|
||||
* vitest. Once the dist worker is wired into the test harness (a Phase 2
|
||||
* follow-up), this file can be extended to swap skipWorkers off. The
|
||||
* load-bearing invariants verified here — multi-chunk parsing
|
||||
* completes within a bounded budget and produces all expected symbols
|
||||
* — catch the bulk of the regressions B3 was concerned about.
|
||||
*/
|
||||
import { describe, it, expect, beforeEach, afterEach, vi } from 'vitest';
|
||||
import fs from 'node:fs';
|
||||
import os from 'node:os';
|
||||
import path from 'node:path';
|
||||
|
||||
const ORIGINAL_BUDGET = process.env.GITNEXUS_CHUNK_BYTE_BUDGET;
|
||||
const WALL_CLOCK_BUDGET_MS = 30_000;
|
||||
|
||||
function buildFixture(): Record<string, string> {
|
||||
const fixture: Record<string, string> = {};
|
||||
for (let i = 0; i < 15; i++) {
|
||||
fixture[`mod${i}.ts`] = `export function fn${i}(): number {\n return ${i};\n}\n`;
|
||||
}
|
||||
// A "realistically dense" file — 30 functions + a class + an interface +
|
||||
// a re-export. Stands in for the kind of file that previously stalled the
|
||||
// serial-extraction chunk loop. Pure-TS so the parser doesn't choke.
|
||||
const complexFnLines = Array.from(
|
||||
{ length: 30 },
|
||||
(_, i) => `export function complex${i}(c: Config): string { return c.name + String(${i}); }`,
|
||||
).join('\n');
|
||||
fixture['complex.ts'] = `
|
||||
export interface Config { name: string; }
|
||||
export class Service {
|
||||
configure(c: Config): void { this.name = c.name; }
|
||||
private name: string = '';
|
||||
describe(): string { return this.name; }
|
||||
}
|
||||
${complexFnLines}
|
||||
`;
|
||||
fixture['index.ts'] =
|
||||
'export { Service, type Config } from "./complex";\n' +
|
||||
Array.from({ length: 15 }, (_, i) => `export { fn${i} } from "./mod${i}";`).join('\n') +
|
||||
'\n';
|
||||
return fixture;
|
||||
}
|
||||
|
||||
async function runFixture(): Promise<{
|
||||
nodeCount: number;
|
||||
relationshipCount: number;
|
||||
symbolNames: Set<string>;
|
||||
elapsedMs: number;
|
||||
}> {
|
||||
const fixture = buildFixture();
|
||||
// Force multi-chunk parsing on the small fixture by lowering the byte
|
||||
// budget below each file's size. parse-impl reads the budget at module
|
||||
// load — vi.resetModules() forces a fresh module so the env takes effect.
|
||||
process.env.GITNEXUS_CHUNK_BYTE_BUDGET = '64';
|
||||
vi.resetModules();
|
||||
const { runChunkedParseAndResolve } =
|
||||
await import('../../src/core/ingestion/pipeline-phases/parse-impl.js');
|
||||
const { createKnowledgeGraph } = await import('../../src/core/graph/graph.js');
|
||||
|
||||
const repoPath = fs.mkdtempSync(path.join(os.tmpdir(), 'parse-impl-large-fixture-'));
|
||||
try {
|
||||
for (const [name, content] of Object.entries(fixture)) {
|
||||
fs.writeFileSync(path.join(repoPath, name), content);
|
||||
}
|
||||
const files = Object.keys(fixture);
|
||||
const scanned = files.map((rel) => ({
|
||||
path: rel,
|
||||
size: fs.statSync(path.join(repoPath, rel)).size,
|
||||
}));
|
||||
const graph = createKnowledgeGraph();
|
||||
|
||||
// Wrap the run in Promise.race so the wall-clock budget is enforced
|
||||
// as an exception, not a >=/<= inequality assertion (DoD §2.7 — a
|
||||
// bounds-only count is a regression-mask; a hard timeout is a
|
||||
// hang-detector). If the run exceeds the budget, the rejection
|
||||
// fails the test with a specific timeout error so the diagnostic
|
||||
// surfaces the actual regression class.
|
||||
const start = Date.now();
|
||||
await Promise.race([
|
||||
runChunkedParseAndResolve(graph, scanned, files, files.length, repoPath, start, () => {}, {
|
||||
skipWorkers: true,
|
||||
}),
|
||||
new Promise<never>((_, reject) =>
|
||||
setTimeout(
|
||||
() =>
|
||||
reject(
|
||||
new Error(
|
||||
`runChunkedParseAndResolve exceeded ${WALL_CLOCK_BUDGET_MS}ms wall-clock budget — likely the hang B3 was meant to prevent`,
|
||||
),
|
||||
),
|
||||
WALL_CLOCK_BUDGET_MS,
|
||||
),
|
||||
),
|
||||
]);
|
||||
const elapsedMs = Date.now() - start;
|
||||
|
||||
const symbolNames = new Set<string>();
|
||||
for (const node of graph.nodes.values()) {
|
||||
const name = (node.properties as { name?: string } | undefined)?.name;
|
||||
if (typeof name === 'string') symbolNames.add(name);
|
||||
}
|
||||
|
||||
return {
|
||||
nodeCount: graph.nodeCount,
|
||||
relationshipCount: graph.relationshipCount,
|
||||
symbolNames,
|
||||
elapsedMs,
|
||||
};
|
||||
} finally {
|
||||
if (fs.existsSync(repoPath)) {
|
||||
fs.rmSync(repoPath, { recursive: true, force: true });
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
describe('parse-impl wall-clock integration on multi-chunk fixture (U6 / B3)', () => {
|
||||
beforeEach(() => {
|
||||
vi.resetModules();
|
||||
});
|
||||
|
||||
afterEach(() => {
|
||||
if (ORIGINAL_BUDGET === undefined) {
|
||||
delete process.env.GITNEXUS_CHUNK_BYTE_BUDGET;
|
||||
} else {
|
||||
process.env.GITNEXUS_CHUNK_BYTE_BUDGET = ORIGINAL_BUDGET;
|
||||
}
|
||||
});
|
||||
|
||||
it('completes a 17-file multi-chunk fixture within wall-clock and indexes every named symbol', async () => {
|
||||
const result = await runFixture();
|
||||
|
||||
// Reaching this assertion means the Promise.race did NOT time out —
|
||||
// the run completed in under WALL_CLOCK_BUDGET_MS. That alone is the
|
||||
// primary B3 invariant: "does not hang on a multi-chunk workload";
|
||||
// the race rejection already enforces it. The previous
|
||||
// `Math.min(elapsedMs, BUDGET)` form here resolved to
|
||||
// `expect(x).toBe(x)` — tautological and catching nothing. The
|
||||
// load-bearing wall-clock check lives in the Promise.race above;
|
||||
// the per-symbol assertions below catch silent mid-chunk crashes.
|
||||
expect(typeof result.elapsedMs).toBe('number');
|
||||
|
||||
// All 15 plain function declarations must show up in the graph.
|
||||
for (let i = 0; i < 15; i++) {
|
||||
expect(result.symbolNames.has(`fn${i}`)).toBe(true);
|
||||
}
|
||||
|
||||
// The complex.ts surfaces: Service class, Config interface, configure
|
||||
// method, and a representative sampling of the complex0..complex29
|
||||
// functions. Pin specific names (not just a count) so chunk-boundary
|
||||
// truncation surfaces as a concrete missing-symbol failure with a
|
||||
// specific diagnostic.
|
||||
expect(result.symbolNames.has('Service')).toBe(true);
|
||||
expect(result.symbolNames.has('Config')).toBe(true);
|
||||
expect(result.symbolNames.has('configure')).toBe(true);
|
||||
expect(result.symbolNames.has('describe')).toBe(true);
|
||||
expect(result.symbolNames.has('complex0')).toBe(true);
|
||||
expect(result.symbolNames.has('complex15')).toBe(true);
|
||||
expect(result.symbolNames.has('complex29')).toBe(true);
|
||||
});
|
||||
});
|
||||
|
|
@ -0,0 +1,388 @@
|
|||
/**
|
||||
* U20 — Integration regression test for chunk-cache corruption on
|
||||
* worker quarantine.
|
||||
*
|
||||
* Pins the fix for the Codex adversarial review finding on PR #1693
|
||||
* (`docs/plans/2026-05-20-002-fix-chunk-cache-corruption-on-worker-quarantine-plan.md`):
|
||||
*
|
||||
* The chunk hash is computed from every file in the chunk, but the
|
||||
* worker pool's Layer 3 quarantine filters quarantined files out of
|
||||
* dispatch. Before the fix, the chunk-loop would cache the partial
|
||||
* worker results under the full-coverage chunk hash, locking in
|
||||
* silent corruption that the next analyze would replay.
|
||||
*
|
||||
* Runs with REAL `worker_threads` + `createWorkerPool`. Injects a
|
||||
* custom worker script via `workerUrlForTest` that:
|
||||
* 1. Implements the U17/U19 IPC protocol (decode Buffer or hybrid
|
||||
* envelope/contents shape, decode header + JSON payload).
|
||||
* 2. Emits a `{type:'ready'}` handshake so the pool's
|
||||
* `waitForWorkerReady` resolves promptly.
|
||||
* 3. On a sub-batch containing `poison.ts`, emits a starting-file
|
||||
* and exits with code 134 — deterministic worker death the pool
|
||||
* attributes to `poison.ts` via the in-flight signal, then
|
||||
* adds to its session-scoped quarantine.
|
||||
* 4. On a sub-batch without poison, synthesizes a minimal valid
|
||||
* ParseWorkerResult with a Function node per file (no
|
||||
* tree-sitter dependency in the test worker — the synthesized
|
||||
* nodes give the merge step deterministic content to add to the
|
||||
* graph).
|
||||
*
|
||||
* U20 design pivot — no sequential fallback. The U1 sequential
|
||||
* reparse for quarantined chunk files was removed: relying on the
|
||||
* worker pool's resilience layers (respawn budget, circuit breaker,
|
||||
* quarantine, slot-attribution, cumulative timeout) as the SOLE
|
||||
* contract avoids re-triggering tree-sitter native crashes on the
|
||||
* main thread and gives operators a clear hard signal when workers
|
||||
* exhaust. Quarantined files are missing from this run's graph;
|
||||
* they're surfaced in the per-chunk warn log; U2's cache-skip keeps
|
||||
* the chunk uncached so the next analyze with a fresh pool retries.
|
||||
*
|
||||
* Assertions exercised here:
|
||||
* - Worker-path runs and produces results for surviving files
|
||||
* (good_a, good_c) via the synthesized worker output.
|
||||
* - The quarantined file (poison.ts) is NOT in the graph — no
|
||||
* sequential reparse fired.
|
||||
* - U2 (cache-write suppression): `parseCache.entries` does NOT
|
||||
* contain the chunk hash after the run. `parseCache.usedKeys`
|
||||
* DOES contain it (chunk was processed; the cache write was
|
||||
* specifically skipped). A cross-run scenario verifies that a
|
||||
* subsequent dispatch with a fresh pool re-attempts the chunk
|
||||
* (cache miss) and the cache stays empty for that chunk.
|
||||
*
|
||||
* Why integration over unit:
|
||||
* - The fix lives at the boundary between processParsing
|
||||
* (`parsing-processor.ts`) and the chunk-loop
|
||||
* (`pipeline-phases/parse-impl.ts`) under a real
|
||||
* workerPool. Unit-mocking the worker-pool import bypasses the
|
||||
* structured-clone boundary, the dispatch lifecycle, and the
|
||||
* actual quarantine flow — it verifies the test setup rather
|
||||
* than the contract. The real worker thread executing the test
|
||||
* script through the U17/U19 IPC protocol IS the load-bearing
|
||||
* surface; this test exercises it end-to-end.
|
||||
* - The `writeReadyWorker` pattern from `worker-pool.test.ts` is
|
||||
* reused inline here (the READY_PREAMBLE + test-worker script
|
||||
* composition).
|
||||
*
|
||||
* Wall-clock budget: well under 5 s under normal CI conditions.
|
||||
*/
|
||||
import { describe, it, expect, afterEach, beforeEach } from 'vitest';
|
||||
import { tmpdir } from 'node:os';
|
||||
import { mkdtempSync, writeFileSync, mkdirSync, rmSync, statSync } from 'node:fs';
|
||||
import path from 'node:path';
|
||||
import { pathToFileURL } from 'node:url';
|
||||
|
||||
import { createKnowledgeGraph } from '../../src/core/graph/graph.js';
|
||||
import { runChunkedParseAndResolve } from '../../src/core/ingestion/pipeline-phases/parse-impl.js';
|
||||
import { computeChunkHash, fileContentHash } from '../../src/storage/parse-cache.js';
|
||||
import type { ParseWorkerResult } from '../../src/core/ingestion/workers/parse-worker.js';
|
||||
|
||||
/**
|
||||
* Inline READY preamble + IPC decode wrapper (mirrors
|
||||
* `test/integration/worker-pool.test.ts`'s READY_PREAMBLE). Lets the
|
||||
* test worker script below speak the production U17/U19 IPC protocol
|
||||
* without importing dist/protocol.js (the script runs as a standalone
|
||||
* CJS file at a temp path, so it can't resolve dist/ via relative
|
||||
* paths reliably).
|
||||
*/
|
||||
const READY_PREAMBLE = `
|
||||
const { parentPort: __pp } = require('node:worker_threads');
|
||||
const __decoder = new TextDecoder('utf-8');
|
||||
const __decodeFrame = (raw) => {
|
||||
if (
|
||||
raw && typeof raw === 'object' &&
|
||||
raw.type === 'sub-batch' &&
|
||||
Array.isArray(raw.files)
|
||||
) {
|
||||
return {
|
||||
type: 'sub-batch',
|
||||
files: raw.files.map((f) => ({
|
||||
path: f.path,
|
||||
content: typeof f.content === 'string' ? f.content : __decoder.decode(f.content),
|
||||
})),
|
||||
};
|
||||
}
|
||||
return raw;
|
||||
};
|
||||
const __origOn = __pp.on.bind(__pp);
|
||||
__pp.on = (event, handler) => {
|
||||
if (event !== 'message') return __origOn(event, handler);
|
||||
return __origOn(event, (raw) => handler(__decodeFrame(raw)));
|
||||
};
|
||||
__pp.postMessage({ type: 'ready' });
|
||||
`;
|
||||
|
||||
/**
|
||||
* Test worker script. Synthesizes minimal ParseWorkerResult entries for
|
||||
* non-poison files; deterministically crashes on poison.ts via
|
||||
* `process.exit(134)`. Accumulates across sub-batches; emits the
|
||||
* accumulated result on `flush`.
|
||||
*/
|
||||
const TEST_WORKER_SCRIPT = `
|
||||
const { parentPort } = require('node:worker_threads');
|
||||
const accumulated = {
|
||||
nodes: [],
|
||||
relationships: [],
|
||||
symbols: [],
|
||||
imports: [],
|
||||
calls: [],
|
||||
assignments: [],
|
||||
heritage: [],
|
||||
routes: [],
|
||||
fetchCalls: [],
|
||||
decoratorRoutes: [],
|
||||
toolDefs: [],
|
||||
ormQueries: [],
|
||||
constructorBindings: [],
|
||||
fileScopeBindings: [],
|
||||
parsedFiles: [],
|
||||
skippedLanguages: {},
|
||||
fileCount: 0,
|
||||
};
|
||||
parentPort.on('message', (msg) => {
|
||||
if (msg && msg.type === 'sub-batch') {
|
||||
const poison = msg.files.find((f) => f.path.endsWith('poison.ts'));
|
||||
if (poison) {
|
||||
parentPort.postMessage({ type: 'starting-file', path: poison.path });
|
||||
process.exit(134);
|
||||
}
|
||||
for (const file of msg.files) {
|
||||
const baseName = file.path.split('/').pop().replace(/\\.ts$/, '');
|
||||
accumulated.nodes.push({
|
||||
id: 'func:' + file.path,
|
||||
label: 'Function',
|
||||
properties: {
|
||||
name: baseName,
|
||||
filePath: file.path,
|
||||
startLine: 1,
|
||||
endLine: 1,
|
||||
language: 'typescript',
|
||||
isExported: true,
|
||||
},
|
||||
});
|
||||
accumulated.fileCount++;
|
||||
}
|
||||
parentPort.postMessage({ type: 'progress', filesProcessed: accumulated.fileCount });
|
||||
parentPort.postMessage({ type: 'sub-batch-done' });
|
||||
return;
|
||||
}
|
||||
if (msg && msg.type === 'flush') {
|
||||
parentPort.postMessage({ type: 'result', data: accumulated });
|
||||
}
|
||||
});
|
||||
`;
|
||||
|
||||
const FIXTURE_FILES = {
|
||||
'src/good_a.ts': 'export function good_a() { return 1; }\n',
|
||||
'src/poison.ts': 'export function poison() { return 2; }\n',
|
||||
'src/good_c.ts': 'export function good_c() { return 3; }\n',
|
||||
};
|
||||
|
||||
describe('U20: parse-impl quarantine + chunk-cache integration (PR #1693 Codex finding)', () => {
|
||||
let tempDir: string;
|
||||
let repoDir: string;
|
||||
let workerPath: string;
|
||||
|
||||
beforeEach(() => {
|
||||
tempDir = mkdtempSync(path.join(tmpdir(), 'parse-impl-quarantine-cache-skip-'));
|
||||
repoDir = path.join(tempDir, 'repo');
|
||||
mkdirSync(repoDir, { recursive: true });
|
||||
|
||||
// Write the fixture files to repoDir so filesystem-walker / chunk
|
||||
// loop pick them up by relative path.
|
||||
for (const [rel, content] of Object.entries(FIXTURE_FILES)) {
|
||||
const full = path.join(repoDir, rel);
|
||||
mkdirSync(path.dirname(full), { recursive: true });
|
||||
writeFileSync(full, content);
|
||||
}
|
||||
|
||||
// Write the test worker script to the same tempDir so it doesn't
|
||||
// collide with anything else. The READY preamble + test script
|
||||
// share one .js file the pool spawns via `new Worker(URL)`.
|
||||
workerPath = path.join(tempDir, 'test-quarantine-worker.js');
|
||||
writeFileSync(workerPath, READY_PREAMBLE + TEST_WORKER_SCRIPT);
|
||||
});
|
||||
|
||||
afterEach(() => {
|
||||
rmSync(tempDir, { recursive: true, force: true });
|
||||
});
|
||||
|
||||
it('worker quarantine leaves poison.ts out of the graph AND suppresses chunk-cache write', async () => {
|
||||
const filePaths = Object.keys(FIXTURE_FILES);
|
||||
const scanned = filePaths.map((rel) => ({
|
||||
path: rel,
|
||||
size: statSync(path.join(repoDir, rel)).size,
|
||||
}));
|
||||
|
||||
// The chunk hash is computed from EVERY file's content hash. The
|
||||
// load-bearing U2 assertion below checks `parseCache.entries.has`
|
||||
// against this exact value, so we compute it the same way
|
||||
// parse-impl does.
|
||||
const expectedChunkHash = computeChunkHash(
|
||||
filePaths.map((p) => ({
|
||||
filePath: p,
|
||||
contentHash: fileContentHash(FIXTURE_FILES[p as keyof typeof FIXTURE_FILES]),
|
||||
})),
|
||||
);
|
||||
|
||||
const parseCache = {
|
||||
version: 'test',
|
||||
entries: new Map<string, ParseWorkerResult[]>(),
|
||||
usedKeys: new Set<string>(),
|
||||
};
|
||||
|
||||
const graph = createKnowledgeGraph();
|
||||
await runChunkedParseAndResolve(
|
||||
graph,
|
||||
scanned,
|
||||
filePaths,
|
||||
filePaths.length,
|
||||
repoDir,
|
||||
Date.now(),
|
||||
() => {},
|
||||
{
|
||||
skipWorkers: false,
|
||||
// Force the worker-pool gate to open on the 3-file fixture.
|
||||
workerThresholdsForTest: { minFiles: 1, minBytes: 1 },
|
||||
// Inject the custom worker script — the pool will spawn it
|
||||
// instead of the production parse-worker.js.
|
||||
workerUrlForTest: pathToFileURL(workerPath) as URL,
|
||||
// Test-only worker pool size — keep at 1 so the poison-file
|
||||
// sub-batch deterministically lands on the only slot (no
|
||||
// chance of poison + good landing in different slots).
|
||||
workerPoolSize: 1,
|
||||
parseCache,
|
||||
},
|
||||
);
|
||||
|
||||
const nodes = Array.from(graph.nodes.values());
|
||||
|
||||
// Quarantine contract: poison.ts is genuinely missing from the
|
||||
// graph for this run. The custom worker crashed on it; no
|
||||
// sequential reparse rescued it; the operator sees the per-chunk
|
||||
// quarantine warn log. A future analyze with a fresh pool gets
|
||||
// another chance via U2's cache-skip below.
|
||||
expect(
|
||||
nodes.some(
|
||||
(n) => n.label === 'Function' && (n.properties as { name?: string }).name === 'poison',
|
||||
),
|
||||
).toBe(false);
|
||||
|
||||
// Surviving files' symbols come from the custom worker's
|
||||
// synthesized output via the normal worker-path merge. Pinning
|
||||
// them here catches a regression that would drop worker results
|
||||
// entirely when quarantine fires.
|
||||
expect(
|
||||
nodes.some(
|
||||
(n) => n.label === 'Function' && (n.properties as { name?: string }).name === 'good_a',
|
||||
),
|
||||
).toBe(true);
|
||||
expect(
|
||||
nodes.some(
|
||||
(n) => n.label === 'Function' && (n.properties as { name?: string }).name === 'good_c',
|
||||
),
|
||||
).toBe(true);
|
||||
|
||||
// U2 assertion: chunk-cache write was suppressed. The chunk hash
|
||||
// is in usedKeys (chunk WAS processed) but absent from entries
|
||||
// (cache write skipped because of the quarantine intersection).
|
||||
// This is the load-bearing cross-run protection: a future analyze
|
||||
// with unchanged content will re-derive the same chunkHash, miss
|
||||
// the cache, and re-dispatch — giving the file another chance
|
||||
// against a fresh-quarantine pool.
|
||||
expect(parseCache.entries.has(expectedChunkHash)).toBe(false);
|
||||
expect(parseCache.usedKeys.has(expectedChunkHash)).toBe(true);
|
||||
expect(parseCache.entries.size).toBe(0);
|
||||
});
|
||||
|
||||
it('cross-run: unchanged fixture re-dispatches on a second pass because the cache was empty', async () => {
|
||||
// First pass: same setup as the previous test. Cache stays empty
|
||||
// because poison.ts triggered quarantine.
|
||||
const filePaths = Object.keys(FIXTURE_FILES);
|
||||
const scanned = filePaths.map((rel) => ({
|
||||
path: rel,
|
||||
size: statSync(path.join(repoDir, rel)).size,
|
||||
}));
|
||||
const expectedChunkHash = computeChunkHash(
|
||||
filePaths.map((p) => ({
|
||||
filePath: p,
|
||||
contentHash: fileContentHash(FIXTURE_FILES[p as keyof typeof FIXTURE_FILES]),
|
||||
})),
|
||||
);
|
||||
|
||||
const parseCache = {
|
||||
version: 'test',
|
||||
entries: new Map<string, ParseWorkerResult[]>(),
|
||||
usedKeys: new Set<string>(),
|
||||
};
|
||||
|
||||
// FIRST PASS.
|
||||
{
|
||||
const graph = createKnowledgeGraph();
|
||||
await runChunkedParseAndResolve(
|
||||
graph,
|
||||
scanned,
|
||||
filePaths,
|
||||
filePaths.length,
|
||||
repoDir,
|
||||
Date.now(),
|
||||
() => {},
|
||||
{
|
||||
skipWorkers: false,
|
||||
workerThresholdsForTest: { minFiles: 1, minBytes: 1 },
|
||||
workerUrlForTest: pathToFileURL(workerPath) as URL,
|
||||
workerPoolSize: 1,
|
||||
parseCache,
|
||||
},
|
||||
);
|
||||
// Confirm the precondition for the second-pass test: cache is
|
||||
// empty for this chunk hash.
|
||||
expect(parseCache.entries.has(expectedChunkHash)).toBe(false);
|
||||
}
|
||||
|
||||
// SECOND PASS — same content, same parseCache, fresh worker pool
|
||||
// (createWorkerPool is called per `runChunkedParseAndResolve`, so
|
||||
// every invocation gets a clean quarantine slate). With the cache
|
||||
// empty for this chunk, the second pass MUST dispatch the chunk
|
||||
// again rather than replaying a cache entry. The custom worker
|
||||
// crashes again on poison.ts → quarantine again → cache still
|
||||
// skipped. Symptom: cache state unchanged, graph still complete.
|
||||
{
|
||||
const graph2 = createKnowledgeGraph();
|
||||
await runChunkedParseAndResolve(
|
||||
graph2,
|
||||
scanned,
|
||||
filePaths,
|
||||
filePaths.length,
|
||||
repoDir,
|
||||
Date.now(),
|
||||
() => {},
|
||||
{
|
||||
skipWorkers: false,
|
||||
workerThresholdsForTest: { minFiles: 1, minBytes: 1 },
|
||||
workerUrlForTest: pathToFileURL(workerPath) as URL,
|
||||
workerPoolSize: 1,
|
||||
parseCache,
|
||||
},
|
||||
);
|
||||
|
||||
// Cache stayed empty (still no entry for this chunk hash) — the
|
||||
// load-bearing cross-run protection.
|
||||
expect(parseCache.entries.has(expectedChunkHash)).toBe(false);
|
||||
expect(parseCache.usedKeys.has(expectedChunkHash)).toBe(true);
|
||||
// Worker path ran again; surviving files in the graph; poison
|
||||
// still absent per the U20 contract (workers are the sole
|
||||
// resilience layer, no sequential reparse).
|
||||
const nodes2 = Array.from(graph2.nodes.values());
|
||||
expect(
|
||||
nodes2.some(
|
||||
(n) => n.label === 'Function' && (n.properties as { name?: string }).name === 'good_a',
|
||||
),
|
||||
).toBe(true);
|
||||
expect(
|
||||
nodes2.some(
|
||||
(n) => n.label === 'Function' && (n.properties as { name?: string }).name === 'poison',
|
||||
),
|
||||
).toBe(false);
|
||||
}
|
||||
});
|
||||
});
|
||||
|
|
@ -1836,6 +1836,64 @@ describe('C++ overload resolution — conversion-rank disambiguation (#1578)', (
|
|||
});
|
||||
});
|
||||
|
||||
// C++ overload resolution: pointer/nullptr/ellipsis conversion ranks (#1637)
|
||||
describe('C++ overload resolution — pointer/nullptr/ellipsis ranks (#1637)', () => {
|
||||
let result: PipelineResult;
|
||||
|
||||
beforeAll(async () => {
|
||||
result = await runPipelineFromRepo(
|
||||
path.join(FIXTURES, 'cpp-overload-pointer-null-ellipsis'),
|
||||
() => {},
|
||||
);
|
||||
}, 60000);
|
||||
|
||||
it('f(nullptr) and f(p) resolve to f(int*) while f(42) resolves to f(bool)', () => {
|
||||
const calls = getRelationships(result, 'CALLS');
|
||||
|
||||
const nullptrCall = calls.find((c) => c.source === 'runNullptr' && c.target === 'f');
|
||||
const pointerCall = calls.find((c) => c.source === 'runPointer' && c.target === 'f');
|
||||
const boolCall = calls.find((c) => c.source === 'runBoolConversion' && c.target === 'f');
|
||||
|
||||
expect(
|
||||
result.graph.getNode(nullptrCall?.rel.targetId ?? '')?.properties.parameterTypes,
|
||||
).toEqual(['int']);
|
||||
expect(
|
||||
result.graph.getNode(pointerCall?.rel.targetId ?? '')?.properties.parameterTypes,
|
||||
).toEqual(['int']);
|
||||
expect(result.graph.getNode(boolCall?.rel.targetId ?? '')?.properties.parameterTypes).toEqual([
|
||||
'bool',
|
||||
]);
|
||||
});
|
||||
|
||||
it('g(1, 2) resolves to fixed-arity g(int, int), not g(int, ...)', () => {
|
||||
const calls = getRelationships(result, 'CALLS');
|
||||
const gCalls = calls.filter((c) => c.source === 'run' && c.target === 'g');
|
||||
|
||||
expect(gCalls.length).toBe(1);
|
||||
const tgt = result.graph.getNode(gCalls[0].rel.targetId);
|
||||
expect(tgt?.properties.parameterTypes).toEqual(['int', 'int']);
|
||||
});
|
||||
|
||||
it("h(1, 'a') resolves to h(int, double), not h(int, ...)", () => {
|
||||
const calls = getRelationships(result, 'CALLS');
|
||||
const hCalls = calls.filter((c) => c.source === 'run' && c.target === 'h');
|
||||
|
||||
expect(hCalls.length).toBe(1);
|
||||
const tgt = result.graph.getNode(hCalls[0].rel.targetId);
|
||||
expect(tgt?.properties.parameterTypes).toEqual(['int', 'double']);
|
||||
});
|
||||
|
||||
it('k(1, 2, 3) keeps the ellipsis overload viable when it is the only match', () => {
|
||||
const calls = getRelationships(result, 'CALLS');
|
||||
const kCalls = calls.filter((c) => c.source === 'run' && c.target === 'k');
|
||||
|
||||
expect(kCalls.length).toBe(1);
|
||||
const tgt = result.graph.getNode(kCalls[0].rel.targetId);
|
||||
expect(tgt?.properties.parameterCount).toBeUndefined();
|
||||
expect(tgt?.properties.parameterTypes).toEqual(['int']);
|
||||
});
|
||||
});
|
||||
|
||||
// ---------------------------------------------------------------------------
|
||||
// U3: anonymous-namespace symbols MUST NOT leak across translation units
|
||||
// (full-pipeline integration test; unit-level coverage exists separately)
|
||||
|
|
@ -3156,6 +3214,59 @@ describe('C++ SFINAE filter — C++20 requires-clause shape', () => {
|
|||
});
|
||||
});
|
||||
|
||||
describe('C++ SFINAE filter — Tier-A type_traits predicates', () => {
|
||||
async function runFixture(name: string): Promise<PipelineResult> {
|
||||
return runPipelineFromRepo(path.join(FIXTURES, name), () => {});
|
||||
}
|
||||
|
||||
function callsFromRunToPick(result: PipelineResult) {
|
||||
return getRelationships(result, 'CALLS').filter(
|
||||
(c) => c.source === 'run' && c.target === 'pick',
|
||||
);
|
||||
}
|
||||
|
||||
it('is_pointer_v and is_class_v disambiguate pointer vs class arguments', async () => {
|
||||
const result = await runFixture('cpp-sfinae-is-pointer');
|
||||
const calls = callsFromRunToPick(result);
|
||||
expect(calls.length).toBe(2);
|
||||
expect(new Set(calls.map((c) => c.rel.targetId)).size).toBe(2);
|
||||
}, 60000);
|
||||
|
||||
it('is_reference_v keeps reference-shaped arguments distinct from values', async () => {
|
||||
const result = await runFixture('cpp-sfinae-is-reference');
|
||||
const calls = callsFromRunToPick(result);
|
||||
expect(calls.length).toBe(2);
|
||||
expect(new Set(calls.map((c) => c.rel.targetId)).size).toBe(2);
|
||||
}, 60000);
|
||||
|
||||
it('is_class_v rejects primitive arguments while keeping class arguments', async () => {
|
||||
const result = await runFixture('cpp-sfinae-is-class');
|
||||
const calls = callsFromRunToPick(result);
|
||||
expect(calls.length).toBe(2);
|
||||
expect(new Set(calls.map((c) => c.rel.targetId)).size).toBe(2);
|
||||
}, 60000);
|
||||
|
||||
it('is_enum_v distinguishes known enum declarations from primitives', async () => {
|
||||
const result = await runFixture('cpp-sfinae-is-enum');
|
||||
const calls = callsFromRunToPick(result);
|
||||
expect(calls.length).toBe(2);
|
||||
expect(new Set(calls.map((c) => c.rel.targetId)).size).toBe(2);
|
||||
}, 60000);
|
||||
|
||||
it('is_const_v and is_volatile_v disambiguate cv-qualified locals', async () => {
|
||||
const result = await runFixture('cpp-sfinae-is-const-volatile');
|
||||
const calls = callsFromRunToPick(result);
|
||||
expect(calls.length).toBe(2);
|
||||
expect(new Set(calls.map((c) => c.rel.targetId)).size).toBe(2);
|
||||
}, 60000);
|
||||
|
||||
it('is_void_v does not misclassify void pointers as void values', async () => {
|
||||
const result = await runFixture('cpp-sfinae-is-void');
|
||||
const calls = callsFromRunToPick(result);
|
||||
expect(calls.length).toBe(1);
|
||||
}, 60000);
|
||||
});
|
||||
|
||||
describe('C++ SFINAE filter — unknown predicate keeps both candidates (monotonicity contract)', () => {
|
||||
let result: PipelineResult;
|
||||
|
||||
|
|
|
|||
|
|
@ -34,6 +34,13 @@ const LEGACY_RESOLVER_PARITY_EXPECTED_FAILURES: Readonly<Record<string, Readonly
|
|||
// which is only available in the registry-primary path.
|
||||
'resolves user.Save() to the method whose receiver type is declared in another package file',
|
||||
]),
|
||||
java: new Set([
|
||||
// Duplicate-FQN same-module path-affinity ordering is implemented in the
|
||||
// Java provider hook for the scope-resolution path. Legacy DAG parity runs
|
||||
// still use legacy owner/type resolution behavior and can bind cross-module.
|
||||
'resolves Module1App.run calls to module1 UserService, not module2',
|
||||
'resolves Module2App.run calls to module2 UserService, not module1',
|
||||
]),
|
||||
php: new Set([
|
||||
// Arity-narrowing in `pickUniqueGlobalCallable` rejects free-call
|
||||
// candidates that are definitively below required-parameter-count. The
|
||||
|
|
@ -189,6 +196,12 @@ const LEGACY_RESOLVER_PARITY_EXPECTED_FAILURES: Readonly<Record<string, Readonly
|
|||
// Multi-arg incomparable overloads: pairwise dominance check finds
|
||||
// neither h(int,int) nor h(double,double) dominates. Scope-resolver-only.
|
||||
'h(42, 2.5) emits zero CALLS edges — incomparable multi-arg overloads, ambiguous',
|
||||
// Pointer/nullptr/ellipsis conversion ranks (#1637) need C++ type-class
|
||||
// sidecars plus conversion-rank scoring. The legacy DAG has neither.
|
||||
'f(nullptr) and f(p) resolve to f(int*) while f(42) resolves to f(bool)',
|
||||
'g(1, 2) resolves to fixed-arity g(int, int), not g(int, ...)',
|
||||
"h(1, 'a') resolves to h(int, double), not h(int, ...)",
|
||||
'k(1, 2, 3) keeps the ellipsis overload viable when it is the only match',
|
||||
// The legacy DAG path lacks the SFINAE / `requires`-clause aware
|
||||
// overload filter (issue #1579). The two `process<T>` overloads
|
||||
// guarded by mutually-exclusive `enable_if_t` predicates collapse
|
||||
|
|
@ -200,6 +213,12 @@ const LEGACY_RESOLVER_PARITY_EXPECTED_FAILURES: Readonly<Record<string, Readonly
|
|||
'enable_if_t<is_integral_v<T>> overload binds only on integral call sites',
|
||||
'enable_if_t<is_floating_point_v<T>> overload binds only on floating call sites',
|
||||
'requires-clause overloads disambiguate same as enable_if_t (F4 AST shape)',
|
||||
'is_pointer_v and is_class_v disambiguate pointer vs class arguments',
|
||||
'is_reference_v keeps reference-shaped arguments distinct from values',
|
||||
'is_class_v rejects primitive arguments while keeping class arguments',
|
||||
'is_enum_v distinguishes known enum declarations from primitives',
|
||||
'is_const_v and is_volatile_v disambiguate cv-qualified locals',
|
||||
'is_void_v does not misclassify void pointers as void values',
|
||||
// The legacy DAG path has no inline-namespace same-name ambiguity
|
||||
// detection. When two inline children declare the same name, the
|
||||
// legacy path picks an arbitrary match. The scope-resolver returns
|
||||
|
|
|
|||
|
|
@ -174,6 +174,72 @@ describe('Java call resolution with arity filtering', () => {
|
|||
});
|
||||
});
|
||||
|
||||
describe('Java same-module priority for duplicate FQNs', () => {
|
||||
let result: PipelineResult;
|
||||
|
||||
beforeAll(async () => {
|
||||
result = await runPipelineFromRepo(path.join(FIXTURES, 'java-duplicate-fqn-modules'), () => {});
|
||||
}, 60000);
|
||||
|
||||
it('resolves Module1App.run calls to module1 UserService, not module2', () => {
|
||||
const calls = getRelationships(result, 'CALLS');
|
||||
const module1ToModule1 = calls.filter(
|
||||
(c) =>
|
||||
c.source === 'run' &&
|
||||
c.target === 'UserService' &&
|
||||
c.sourceFilePath === 'module1/src/main/java/com/example/Module1App.java' &&
|
||||
c.targetFilePath === 'module1/src/main/java/com/example/UserService.java',
|
||||
);
|
||||
const module1ToModule2 = calls.filter(
|
||||
(c) =>
|
||||
c.source === 'run' &&
|
||||
c.target === 'UserService' &&
|
||||
c.sourceFilePath === 'module1/src/main/java/com/example/Module1App.java' &&
|
||||
c.targetFilePath === 'module2/src/main/java/com/example/UserService.java',
|
||||
);
|
||||
const module1ToAnyUserService = calls.filter(
|
||||
(c) =>
|
||||
c.source === 'run' &&
|
||||
c.target === 'UserService' &&
|
||||
c.sourceFilePath === 'module1/src/main/java/com/example/Module1App.java' &&
|
||||
/module[12]\/src\/main\/java\/com\/example\/UserService\.java/.test(c.targetFilePath),
|
||||
);
|
||||
|
||||
expect(module1ToModule1.length).toBe(1);
|
||||
expect(module1ToModule2.length).toBe(0);
|
||||
expect(module1ToAnyUserService.length).toBe(1);
|
||||
});
|
||||
|
||||
it('resolves Module2App.run calls to module2 UserService, not module1', () => {
|
||||
const calls = getRelationships(result, 'CALLS');
|
||||
const module2ToModule2 = calls.filter(
|
||||
(c) =>
|
||||
c.source === 'run' &&
|
||||
c.target === 'UserService' &&
|
||||
c.sourceFilePath === 'module2/src/main/java/com/example/Module2App.java' &&
|
||||
c.targetFilePath === 'module2/src/main/java/com/example/UserService.java',
|
||||
);
|
||||
const module2ToModule1 = calls.filter(
|
||||
(c) =>
|
||||
c.source === 'run' &&
|
||||
c.target === 'UserService' &&
|
||||
c.sourceFilePath === 'module2/src/main/java/com/example/Module2App.java' &&
|
||||
c.targetFilePath === 'module1/src/main/java/com/example/UserService.java',
|
||||
);
|
||||
const module2ToAnyUserService = calls.filter(
|
||||
(c) =>
|
||||
c.source === 'run' &&
|
||||
c.target === 'UserService' &&
|
||||
c.sourceFilePath === 'module2/src/main/java/com/example/Module2App.java' &&
|
||||
/module[12]\/src\/main\/java\/com\/example\/UserService\.java/.test(c.targetFilePath),
|
||||
);
|
||||
|
||||
expect(module2ToModule2.length).toBe(1);
|
||||
expect(module2ToModule1.length).toBe(0);
|
||||
expect(module2ToAnyUserService.length).toBe(1);
|
||||
});
|
||||
});
|
||||
|
||||
// ---------------------------------------------------------------------------
|
||||
// Member-call resolution: obj.method() resolves through pipeline
|
||||
// ---------------------------------------------------------------------------
|
||||
|
|
|
|||
|
|
@ -7,7 +7,11 @@
|
|||
* but workers need compiled .js files.
|
||||
*/
|
||||
import { describe, it, expect, afterEach } from 'vitest';
|
||||
import { createWorkerPool, WorkerPool } from '../../src/core/ingestion/workers/worker-pool.js';
|
||||
import {
|
||||
createWorkerPool,
|
||||
WorkerPool,
|
||||
WorkerPoolDispatchError,
|
||||
} from '../../src/core/ingestion/workers/worker-pool.js';
|
||||
import { pathToFileURL } from 'node:url';
|
||||
import path from 'node:path';
|
||||
import fs from 'node:fs';
|
||||
|
|
@ -26,10 +30,59 @@ const DIST_WORKER = path.resolve(
|
|||
);
|
||||
const hasDistWorker = fs.existsSync(DIST_WORKER);
|
||||
|
||||
// Prepend two things to every ad-hoc test worker source:
|
||||
//
|
||||
// 1. The ready handshake so the pool's `waitForWorkerReady` resolves
|
||||
// immediately for replacement spawns. Production `parse-worker.ts`
|
||||
// emits the same handshake at top-of-script before installing its
|
||||
// message handler. Without it, every test that triggers a
|
||||
// replacement (worker crash + recover) would hit the 5s
|
||||
// WORKER_READY_TIMEOUT_MS and fail with "Replacement worker startup
|
||||
// failed and no slots remain".
|
||||
//
|
||||
// 2. A `parentPort.on('message', ...)` wrapper that converts the
|
||||
// sub-batch `files[i].content` field from `Uint8Array`
|
||||
// (transferred zero-copy by the pool) back to `string` for the
|
||||
// ad-hoc test worker scripts. Production `parse-worker.ts` does
|
||||
// this lazily at the tree-sitter call site; test scripts assume
|
||||
// `msg.files[i].content` is already a string. Without this
|
||||
// conversion, the test scripts would need to decode each content
|
||||
// Uint8Array themselves.
|
||||
const READY_PREAMBLE = `
|
||||
const { parentPort: __pp } = require('node:worker_threads');
|
||||
const __decoder = new TextDecoder('utf-8');
|
||||
const __decodeFrame = (raw) => {
|
||||
if (
|
||||
raw && typeof raw === 'object' &&
|
||||
raw.type === 'sub-batch' &&
|
||||
Array.isArray(raw.files)
|
||||
) {
|
||||
return {
|
||||
type: 'sub-batch',
|
||||
files: raw.files.map((f) => ({
|
||||
path: f.path,
|
||||
content: typeof f.content === 'string' ? f.content : __decoder.decode(f.content),
|
||||
})),
|
||||
};
|
||||
}
|
||||
return raw;
|
||||
};
|
||||
const __origOn = __pp.on.bind(__pp);
|
||||
__pp.on = (event, handler) => {
|
||||
if (event !== 'message') return __origOn(event, handler);
|
||||
return __origOn(event, (raw) => handler(__decodeFrame(raw)));
|
||||
};
|
||||
__pp.postMessage({ type: 'ready' });
|
||||
`;
|
||||
|
||||
function writeReadyWorker(workerPath: string, source: string): void {
|
||||
fs.writeFileSync(workerPath, READY_PREAMBLE + source);
|
||||
}
|
||||
|
||||
function writeTempWorker(prefix: string, source: string): { tempDir: string; workerPath: string } {
|
||||
const tempDir = fs.mkdtempSync(path.join(os.tmpdir(), prefix));
|
||||
const workerPath = path.join(tempDir, 'worker.js');
|
||||
fs.writeFileSync(workerPath, source);
|
||||
writeReadyWorker(workerPath, source);
|
||||
return { tempDir, workerPath };
|
||||
}
|
||||
|
||||
|
|
@ -76,9 +129,8 @@ describe('worker pool integration', () => {
|
|||
expect(results).toHaveLength(1);
|
||||
const result = results[0];
|
||||
expect(result.fileCount).toBe(1);
|
||||
expect(result.nodes.length).toBeGreaterThan(0);
|
||||
|
||||
// Should find the validateInput function
|
||||
// Stronger than `nodes.length > 0`: the file MUST emit the
|
||||
// validateInput function symbol or the parse is broken.
|
||||
const names = result.nodes.map((n: any) => n.properties.name);
|
||||
expect(names).toContain('validateInput');
|
||||
});
|
||||
|
|
@ -96,12 +148,18 @@ describe('worker pool integration', () => {
|
|||
content: fs.readFileSync(path.join(fixturesDir, f), 'utf-8'),
|
||||
}));
|
||||
|
||||
expect(files.length).toBeGreaterThanOrEqual(4);
|
||||
// mini-repo/src/ ships exactly 7 .ts files (db, formatter, handler,
|
||||
// index, logger, middleware, validator). Pinning the count surfaces
|
||||
// a fixture change as a test signal instead of letting the rest of
|
||||
// the test silently rebalance.
|
||||
expect(files.length).toBe(7);
|
||||
|
||||
const results = await pool.dispatch<any, any>(files);
|
||||
|
||||
// Each worker chunk returns a result
|
||||
expect(results.length).toBeGreaterThan(0);
|
||||
// All 7 files fit one default sub-batch (size 200 / budget 8MB),
|
||||
// so the dispatch returns exactly one chunk result regardless of
|
||||
// pool size.
|
||||
expect(results).toHaveLength(1);
|
||||
|
||||
// Total files parsed should match input
|
||||
const totalParsed = results.reduce((sum: number, r: any) => sum + r.fileCount, 0);
|
||||
|
|
@ -189,7 +247,13 @@ describe('worker pool integration', () => {
|
|||
expect(results).toHaveLength(1);
|
||||
const result = results[0];
|
||||
expect(typeof result.fileCount).toBe('number');
|
||||
expect(result.fileCount).toBeGreaterThanOrEqual(0);
|
||||
// Empty content → tree-sitter parse produces no symbols. The
|
||||
// fileCount on the result reflects how many files the worker
|
||||
// successfully processed (1 in this case — an empty file is still
|
||||
// "processed", just without emitting symbols). Pinning exactly 1
|
||||
// catches a regression that would silently start dropping
|
||||
// empty-content files from the count.
|
||||
expect(result.fileCount).toBe(1);
|
||||
expect(Array.isArray(result.nodes)).toBe(true);
|
||||
},
|
||||
);
|
||||
|
|
@ -277,7 +341,7 @@ describe('worker pool integration', () => {
|
|||
const tempDir = fs.mkdtempSync(path.join(os.tmpdir(), 'gitnexus-worker-retry-'));
|
||||
const markerPath = path.join(tempDir, 'first-attempt.txt');
|
||||
const workerPath = path.join(tempDir, 'worker.js');
|
||||
fs.writeFileSync(
|
||||
writeReadyWorker(
|
||||
workerPath,
|
||||
`
|
||||
const fs = require('node:fs');
|
||||
|
|
@ -323,7 +387,7 @@ describe('worker pool integration', () => {
|
|||
const tempDir = fs.mkdtempSync(path.join(os.tmpdir(), 'gitnexus-worker-replace-fail-'));
|
||||
const markerPath = path.join(tempDir, 'first-attempt.txt');
|
||||
const workerPath = path.join(tempDir, 'worker.js');
|
||||
fs.writeFileSync(
|
||||
writeReadyWorker(
|
||||
workerPath,
|
||||
`
|
||||
const fs = require('node:fs');
|
||||
|
|
@ -353,11 +417,30 @@ describe('worker pool integration', () => {
|
|||
});
|
||||
|
||||
try {
|
||||
await expect(pool.dispatch<any, any>([{ path: 'crash.ts', content: '' }])).rejects.toThrow(
|
||||
/simulated startup crash|exited with code|idle timeout/,
|
||||
);
|
||||
// Resilience refactor (PR #1693): even with a startup-crashing
|
||||
// replacement worker, Node's `online` event fires BEFORE the
|
||||
// worker's main script runs — `waitForWorkerOnline` resolves
|
||||
// optimistically, the slot is re-occupied with a doomed worker,
|
||||
// the second idle timeout triggers the give-up path, and the
|
||||
// file is quarantined. Dispatch resolves with empty results and
|
||||
// the file is in quarantine. A warning is still emitted for the
|
||||
// operator. Documented race: `waitForWorkerOnline` does not wait
|
||||
// for a grace period after `online` before resolving.
|
||||
const results = await pool.dispatch<any, any>([{ path: 'crash.ts', content: '' }]);
|
||||
expect(results).toEqual([]);
|
||||
expect(pool.getQuarantinedPaths?.() ?? []).toEqual(['crash.ts']);
|
||||
const warnRecords = cap.records().filter((r) => Number(r.level) >= 40 /* warn or above */);
|
||||
expect(warnRecords.length).toBeGreaterThan(0);
|
||||
// The pool must emit at least one warn naming the crash recovery
|
||||
// path so an operator can distinguish a startup-crash from a
|
||||
// stalled-worker rejection. Content match is stronger than a
|
||||
// length bound: a future refactor that drops the warning would
|
||||
// pass a length check but fail this predicate.
|
||||
const sawRecoveryWarn = warnRecords.some(
|
||||
(r) =>
|
||||
typeof r.msg === 'string' &&
|
||||
/(respawn|dropping slot|replacement|did not report ready|exceeded respawn)/i.test(r.msg),
|
||||
);
|
||||
expect(sawRecoveryWarn).toBe(true);
|
||||
} finally {
|
||||
cap.restore();
|
||||
fs.rmSync(tempDir, { recursive: true, force: true });
|
||||
|
|
@ -368,7 +451,7 @@ describe('worker pool integration', () => {
|
|||
const tempDir = fs.mkdtempSync(path.join(os.tmpdir(), 'gitnexus-worker-split-'));
|
||||
const markerPath = path.join(tempDir, 'stalled-once.txt');
|
||||
const workerPath = path.join(tempDir, 'worker.js');
|
||||
fs.writeFileSync(
|
||||
writeReadyWorker(
|
||||
workerPath,
|
||||
`
|
||||
const fs = require('node:fs');
|
||||
|
|
@ -430,7 +513,12 @@ describe('worker pool integration', () => {
|
|||
}
|
||||
});
|
||||
|
||||
it('rejects a persistently stalled singleton so the caller can fall back sequentially', async () => {
|
||||
it('quarantines a persistently stalled singleton so subsequent dispatches skip it', async () => {
|
||||
// Resilience refactor (PR #1693): a singleton-timeout no longer
|
||||
// rejects the whole dispatch. The stalled file is quarantined and
|
||||
// the slot respawns; the dispatch resolves with empty results (no
|
||||
// files parsed). Subsequent dispatches with the same path filter it
|
||||
// out via the pool's quarantine.
|
||||
const { tempDir, workerPath } = writeTempWorker(
|
||||
'gitnexus-worker-stalled-',
|
||||
`
|
||||
|
|
@ -444,12 +532,14 @@ describe('worker pool integration', () => {
|
|||
pool = createWorkerPool(pathToFileURL(workerPath) as URL, 1, {
|
||||
subBatchIdleTimeoutMs: 150,
|
||||
maxTimeoutRetries: 0,
|
||||
consecutiveFailureThreshold: 10,
|
||||
maxRespawnsPerSlot: 3,
|
||||
});
|
||||
|
||||
try {
|
||||
await expect(pool.dispatch<any, any>([{ path: 'stalled.ts', content: '' }])).rejects.toThrow(
|
||||
/sequential fallback/,
|
||||
);
|
||||
const results = await pool.dispatch<any, any>([{ path: 'stalled.ts', content: '' }]);
|
||||
expect(results).toEqual([]);
|
||||
expect(pool.getQuarantinedPaths?.() ?? []).toEqual(['stalled.ts']);
|
||||
} finally {
|
||||
fs.rmSync(tempDir, { recursive: true, force: true });
|
||||
}
|
||||
|
|
@ -459,7 +549,7 @@ describe('worker pool integration', () => {
|
|||
const tempDir = fs.mkdtempSync(path.join(os.tmpdir(), 'gitnexus-worker-race-'));
|
||||
const markerPath = path.join(tempDir, 'stalled-once.txt');
|
||||
const workerPath = path.join(tempDir, 'worker.js');
|
||||
fs.writeFileSync(
|
||||
writeReadyWorker(
|
||||
workerPath,
|
||||
`
|
||||
const fs = require('node:fs');
|
||||
|
|
@ -532,7 +622,7 @@ describe('worker pool integration', () => {
|
|||
const tempDir = fs.mkdtempSync(path.join(os.tmpdir(), 'gitnexus-worker-sole-active-'));
|
||||
const markerPath = path.join(tempDir, 'stalled-once.txt');
|
||||
const workerPath = path.join(tempDir, 'worker.js');
|
||||
fs.writeFileSync(
|
||||
writeReadyWorker(
|
||||
workerPath,
|
||||
`
|
||||
const fs = require('node:fs');
|
||||
|
|
@ -604,8 +694,10 @@ describe('worker pool integration', () => {
|
|||
await expect(pool.dispatch<any, any>([{ path: 'bad.ts', content: '' }])).rejects.toThrow(
|
||||
/protocol error/,
|
||||
);
|
||||
// Resilience refactor (PR #1693): subsequent dispatches reject with
|
||||
// the circuit-breaker message instead of the prior-failure wording.
|
||||
await expect(pool.dispatch<any, any>([{ path: 'after.ts', content: '' }])).rejects.toThrow(
|
||||
/previous failure.*protocol error/,
|
||||
/circuit breaker.*protocol error/i,
|
||||
);
|
||||
} finally {
|
||||
fs.rmSync(tempDir, { recursive: true, force: true });
|
||||
|
|
@ -668,4 +760,378 @@ describe('worker pool integration', () => {
|
|||
await zeroPool.terminate();
|
||||
}
|
||||
});
|
||||
|
||||
// --- Resilience layers (PR #1693 follow-on) ----------------------------
|
||||
|
||||
it('respawns the slot after worker process.exit and finishes the work on the replacement', async () => {
|
||||
// Worker exits with code 1 on its first sub-batch, then the replacement
|
||||
// processes whatever lands in its sub-batch successfully. Exercises
|
||||
// Layer 1 auto-respawn + Layer 3 quarantine end-to-end through real
|
||||
// worker IPC and real waitForWorkerOnline timing.
|
||||
const tempDir = fs.mkdtempSync(path.join(os.tmpdir(), 'gitnexus-resilience-respawn-'));
|
||||
const markerPath = path.join(tempDir, 'crashed-once.txt');
|
||||
const workerPath = path.join(tempDir, 'worker.js');
|
||||
writeReadyWorker(
|
||||
workerPath,
|
||||
`
|
||||
const fs = require('node:fs');
|
||||
const { parentPort } = require('node:worker_threads');
|
||||
const markerPath = ${JSON.stringify(markerPath)};
|
||||
let current = [];
|
||||
parentPort.on('message', (msg) => {
|
||||
if (msg && msg.type === 'sub-batch') {
|
||||
current = msg.files.map((file) => file.path);
|
||||
if (!fs.existsSync(markerPath)) {
|
||||
fs.writeFileSync(markerPath, 'crash once');
|
||||
parentPort.postMessage({ type: 'starting-file', path: current[0] });
|
||||
process.exit(134);
|
||||
}
|
||||
parentPort.postMessage({ type: 'progress', filesProcessed: current.length });
|
||||
parentPort.postMessage({ type: 'sub-batch-done' });
|
||||
return;
|
||||
}
|
||||
if (msg && msg.type === 'flush') {
|
||||
parentPort.postMessage({ type: 'result', data: { fileCount: current.length, paths: current } });
|
||||
}
|
||||
});
|
||||
`,
|
||||
);
|
||||
|
||||
pool = createWorkerPool(pathToFileURL(workerPath) as URL, 1, {
|
||||
subBatchIdleTimeoutMs: 2000,
|
||||
consecutiveFailureThreshold: 5,
|
||||
maxRespawnsPerSlot: 3,
|
||||
});
|
||||
|
||||
try {
|
||||
const results = await pool.dispatch<
|
||||
{ path: string; content: string },
|
||||
{ fileCount: number; paths: string[] }
|
||||
>([
|
||||
{ path: 'killer.ts', content: '' },
|
||||
{ path: 'good.ts', content: '' },
|
||||
]);
|
||||
// killer.ts was quarantined; replacement processes only the
|
||||
// non-quarantined remainder.
|
||||
expect(results.length).toBe(1);
|
||||
expect(results[0].paths).toEqual(['good.ts']);
|
||||
expect(pool.getQuarantinedPaths?.() ?? []).toEqual(['killer.ts']);
|
||||
} finally {
|
||||
fs.rmSync(tempDir, { recursive: true, force: true });
|
||||
}
|
||||
});
|
||||
|
||||
it('attributes exactly via authoritative starting-file message on worker crash', async () => {
|
||||
// Worker emits starting-file for the SECOND file, then crashes. The
|
||||
// pool must quarantine exactly that file (not items[0] from the
|
||||
// heuristic). Validates Layer 4 end-to-end through real IPC ordering.
|
||||
const { tempDir, workerPath } = writeTempWorker(
|
||||
'gitnexus-resilience-attribution-',
|
||||
`
|
||||
const { parentPort } = require('node:worker_threads');
|
||||
let current = [];
|
||||
parentPort.on('message', (msg) => {
|
||||
if (msg && msg.type === 'sub-batch') {
|
||||
current = msg.files.map((file) => file.path);
|
||||
// Pretend we successfully processed the first file, then crash
|
||||
// mid-second.
|
||||
parentPort.postMessage({ type: 'starting-file', path: current[0] });
|
||||
parentPort.postMessage({ type: 'progress', filesProcessed: 1 });
|
||||
parentPort.postMessage({ type: 'starting-file', path: current[1] });
|
||||
process.exit(134);
|
||||
}
|
||||
});
|
||||
`,
|
||||
);
|
||||
|
||||
pool = createWorkerPool(pathToFileURL(workerPath) as URL, 1, {
|
||||
subBatchIdleTimeoutMs: 2000,
|
||||
consecutiveFailureThreshold: 5,
|
||||
maxRespawnsPerSlot: 1,
|
||||
});
|
||||
|
||||
try {
|
||||
// Job dies, respawn re-tries with filtered job (without items[1]
|
||||
// and items[0] since items[0] was already processed but flush
|
||||
// never landed). Second worker crashes on items[0] of the
|
||||
// re-queued job (which is the original items[0]); slot drops
|
||||
// after budget=1 exceeded.
|
||||
await expect(
|
||||
pool.dispatch<{ path: string; content: string }, unknown>([
|
||||
{ path: 'first.ts', content: '' },
|
||||
{ path: 'second-mid-crash.ts', content: '' },
|
||||
{ path: 'third.ts', content: '' },
|
||||
]),
|
||||
).rejects.toBeInstanceOf(WorkerPoolDispatchError);
|
||||
// The crash attribution names the file authoritatively from the
|
||||
// starting-file message, not items[0].
|
||||
const quarantine = pool.getQuarantinedPaths?.() ?? [];
|
||||
expect(quarantine).toContain('second-mid-crash.ts');
|
||||
} finally {
|
||||
fs.rmSync(tempDir, { recursive: true, force: true });
|
||||
}
|
||||
});
|
||||
|
||||
it('quarantine filters subsequent dispatches without sending to a worker', async () => {
|
||||
// After dispatch A quarantines path X, dispatch B with X in input
|
||||
// must NOT include X in the sub-batch the worker receives. Records
|
||||
// the paths each sub-batch sees.
|
||||
const tempDir = fs.mkdtempSync(
|
||||
path.join(os.tmpdir(), 'gitnexus-resilience-quarantine-filter-'),
|
||||
);
|
||||
const seenPath = path.join(tempDir, 'sub-batches.json');
|
||||
const markerPath = path.join(tempDir, 'crashed-once.txt');
|
||||
const workerPath = path.join(tempDir, 'worker.js');
|
||||
writeReadyWorker(
|
||||
workerPath,
|
||||
`
|
||||
const fs = require('node:fs');
|
||||
const { parentPort } = require('node:worker_threads');
|
||||
const seenPath = ${JSON.stringify(seenPath)};
|
||||
const markerPath = ${JSON.stringify(markerPath)};
|
||||
let current = [];
|
||||
function recordSeen(paths) {
|
||||
const prior = fs.existsSync(seenPath) ? JSON.parse(fs.readFileSync(seenPath, 'utf-8')) : [];
|
||||
prior.push(paths);
|
||||
fs.writeFileSync(seenPath, JSON.stringify(prior));
|
||||
}
|
||||
parentPort.on('message', (msg) => {
|
||||
if (msg && msg.type === 'sub-batch') {
|
||||
current = msg.files.map((f) => f.path);
|
||||
recordSeen(current);
|
||||
if (!fs.existsSync(markerPath) && current.includes('poison.ts')) {
|
||||
fs.writeFileSync(markerPath, 'crash once on poison');
|
||||
parentPort.postMessage({ type: 'starting-file', path: 'poison.ts' });
|
||||
process.exit(134);
|
||||
}
|
||||
parentPort.postMessage({ type: 'progress', filesProcessed: current.length });
|
||||
parentPort.postMessage({ type: 'sub-batch-done' });
|
||||
return;
|
||||
}
|
||||
if (msg && msg.type === 'flush') {
|
||||
parentPort.postMessage({ type: 'result', data: { fileCount: current.length, paths: current } });
|
||||
}
|
||||
});
|
||||
`,
|
||||
);
|
||||
|
||||
pool = createWorkerPool(pathToFileURL(workerPath) as URL, 1, {
|
||||
subBatchIdleTimeoutMs: 2000,
|
||||
consecutiveFailureThreshold: 5,
|
||||
maxRespawnsPerSlot: 3,
|
||||
});
|
||||
|
||||
try {
|
||||
// Dispatch A quarantines poison.ts.
|
||||
await pool.dispatch<{ path: string; content: string }, unknown>([
|
||||
{ path: 'poison.ts', content: '' },
|
||||
{ path: 'companion.ts', content: '' },
|
||||
]);
|
||||
expect(pool.getQuarantinedPaths?.() ?? []).toEqual(['poison.ts']);
|
||||
|
||||
// Dispatch B includes poison.ts; pool must filter it out before
|
||||
// the worker sees it.
|
||||
const results = await pool.dispatch<{ path: string; content: string }, { paths: string[] }>([
|
||||
{ path: 'poison.ts', content: '' },
|
||||
{ path: 'fresh.ts', content: '' },
|
||||
]);
|
||||
expect(results.length).toBe(1);
|
||||
expect(results[0].paths).toEqual(['fresh.ts']);
|
||||
|
||||
// Audit: which sub-batches did the worker actually receive?
|
||||
const allSubBatches: string[][] = JSON.parse(fs.readFileSync(seenPath, 'utf-8'));
|
||||
const dispatchBSubBatches = allSubBatches.slice(-1);
|
||||
expect(dispatchBSubBatches[0]).toEqual(['fresh.ts']);
|
||||
// No sub-batch sent during dispatch B contained 'poison.ts'.
|
||||
expect(dispatchBSubBatches.some((b) => b.includes('poison.ts'))).toBe(false);
|
||||
} finally {
|
||||
fs.rmSync(tempDir, { recursive: true, force: true });
|
||||
}
|
||||
});
|
||||
|
||||
it('drops a slot after maxRespawnsPerSlot and continues on the survivor', async () => {
|
||||
// 2-worker pool, budget=1. The worker that's assigned the chunk
|
||||
// containing `a.ts` crashes on a.ts (quarantines a), respawns, gets
|
||||
// the requeued remainder containing `b.ts`, crashes on b.ts
|
||||
// (quarantines b). That slot's respawn budget is now exhausted, so
|
||||
// the pool drops it. The OTHER slot — assigned the chunk with
|
||||
// [c,d] — never sees the poison files and completes its work
|
||||
// normally. Validates the per-slot drop + wakeIdleSlots flow under
|
||||
// real worker timing.
|
||||
//
|
||||
// The path-based crash trigger replaces an earlier shared-counter-
|
||||
// file design that was a write-write race between the two workers:
|
||||
// pre-U17 timing happened to land on counter=2 by the end of
|
||||
// round 1 (so round-2 workers saw counter==2 and didn't crash),
|
||||
// but the post-U17 protocol-decoding latency shifted the window
|
||||
// so round 2's first worker read counter=1 and crashed too,
|
||||
// producing 3 quarantines instead of 2. Switching to a path-based
|
||||
// trigger removes the inter-worker race entirely — the outcome
|
||||
// depends only on which chunk contains the poison files, which is
|
||||
// deterministic given the dispatch ordering of [a,b,c,d] with
|
||||
// subBatchSize=2.
|
||||
const tempDir = fs.mkdtempSync(path.join(os.tmpdir(), 'gitnexus-resilience-slot-drop-'));
|
||||
const workerPath = path.join(tempDir, 'worker.js');
|
||||
writeReadyWorker(
|
||||
workerPath,
|
||||
`
|
||||
const { parentPort } = require('node:worker_threads');
|
||||
let current = [];
|
||||
parentPort.on('message', (msg) => {
|
||||
if (msg && msg.type === 'sub-batch') {
|
||||
current = msg.files.map((f) => f.path);
|
||||
// Crash deterministically on the poison files. The pool
|
||||
// filters quarantined paths from subsequent re-dispatches,
|
||||
// so the first crash quarantines a.ts and the requeue then
|
||||
// contains b.ts; the second crash quarantines b.ts and the
|
||||
// slot's respawn budget is exhausted. Worker handling the
|
||||
// [c,d] chunk never enters this branch.
|
||||
const poison = current.find((p) => p === 'a.ts' || p === 'b.ts');
|
||||
if (poison) {
|
||||
parentPort.postMessage({ type: 'starting-file', path: poison });
|
||||
process.exit(134);
|
||||
}
|
||||
parentPort.postMessage({ type: 'progress', filesProcessed: current.length });
|
||||
parentPort.postMessage({ type: 'sub-batch-done' });
|
||||
return;
|
||||
}
|
||||
if (msg && msg.type === 'flush') {
|
||||
parentPort.postMessage({ type: 'result', data: { paths: current } });
|
||||
}
|
||||
});
|
||||
`,
|
||||
);
|
||||
|
||||
pool = createWorkerPool(pathToFileURL(workerPath) as URL, 2, {
|
||||
subBatchSize: 2,
|
||||
subBatchIdleTimeoutMs: 2000,
|
||||
consecutiveFailureThreshold: 10,
|
||||
maxRespawnsPerSlot: 1,
|
||||
});
|
||||
|
||||
try {
|
||||
const results = await pool.dispatch<{ path: string; content: string }, { paths: string[] }>([
|
||||
{ path: 'a.ts', content: '' },
|
||||
{ path: 'b.ts', content: '' },
|
||||
{ path: 'c.ts', content: '' },
|
||||
{ path: 'd.ts', content: '' },
|
||||
]);
|
||||
|
||||
// Deterministically: a.ts crashes round 1, b.ts crashes round 2.
|
||||
const quarantine = (pool.getQuarantinedPaths?.() ?? []).sort();
|
||||
expect(quarantine).toEqual(['a.ts', 'b.ts']);
|
||||
// All non-quarantined files eventually parsed by the survivor slot.
|
||||
const allPaths = results.flatMap((r) => r.paths).sort();
|
||||
expect(allPaths).toEqual(['c.ts', 'd.ts']);
|
||||
} finally {
|
||||
fs.rmSync(tempDir, { recursive: true, force: true });
|
||||
}
|
||||
});
|
||||
|
||||
it('trips the circuit breaker on cascading per-slot consecutive failures', async () => {
|
||||
// Single-slot pool with consecutiveFailureThreshold=2. Worker dies
|
||||
// on every job; after 2 consecutive deaths on slot 0 the breaker
|
||||
// trips and dispatch rejects with WorkerPoolDispatchError.
|
||||
const { tempDir, workerPath } = writeTempWorker(
|
||||
'gitnexus-resilience-breaker-',
|
||||
`
|
||||
const { parentPort } = require('node:worker_threads');
|
||||
parentPort.on('message', (msg) => {
|
||||
if (msg && msg.type === 'sub-batch') {
|
||||
const path = msg.files[0]?.path;
|
||||
if (path) parentPort.postMessage({ type: 'starting-file', path });
|
||||
process.exit(134);
|
||||
}
|
||||
});
|
||||
`,
|
||||
);
|
||||
|
||||
pool = createWorkerPool(pathToFileURL(workerPath) as URL, 1, {
|
||||
subBatchIdleTimeoutMs: 2000,
|
||||
consecutiveFailureThreshold: 2,
|
||||
maxRespawnsPerSlot: 5,
|
||||
});
|
||||
|
||||
try {
|
||||
const err = await pool
|
||||
.dispatch<{ path: string; content: string }, unknown>([
|
||||
{ path: 'one.ts', content: '' },
|
||||
{ path: 'two.ts', content: '' },
|
||||
])
|
||||
.catch((e) => e);
|
||||
expect(err).toBeInstanceOf(WorkerPoolDispatchError);
|
||||
const dispatchErr = err as WorkerPoolDispatchError;
|
||||
// Breaker tripped with the cumulative quarantine surfaced for
|
||||
// sequential fallback. With threshold=2 + single-slot pool +
|
||||
// both items crashing in sequence, both files are in-flight
|
||||
// when their respective deaths fire, so both end up in
|
||||
// quarantine before the breaker trips. Pinning the exact set is
|
||||
// stronger than `length > 0` and surfaces a regression where
|
||||
// only one path makes it through.
|
||||
expect([...dispatchErr.quarantinedPaths].sort()).toEqual(['one.ts', 'two.ts']);
|
||||
expect(/circuit breaker tripped/i.test(dispatchErr.message)).toBe(true);
|
||||
|
||||
// Subsequent dispatch rejects up front with the same error class.
|
||||
await expect(
|
||||
pool.dispatch<{ path: string; content: string }, unknown>([
|
||||
{ path: 'after.ts', content: '' },
|
||||
]),
|
||||
).rejects.toBeInstanceOf(WorkerPoolDispatchError);
|
||||
} finally {
|
||||
fs.rmSync(tempDir, { recursive: true, force: true });
|
||||
}
|
||||
});
|
||||
|
||||
it('survives a worker `error` event (uncaught throw) the same as a process.exit', async () => {
|
||||
// Worker throws an uncaught error on first sub-batch (triggers Node
|
||||
// Worker 'error' event), then the replacement succeeds. Validates
|
||||
// recoverAndResume on the errorHandler path with real async timing.
|
||||
const tempDir = fs.mkdtempSync(path.join(os.tmpdir(), 'gitnexus-resilience-error-event-'));
|
||||
const markerPath = path.join(tempDir, 'thrown-once.txt');
|
||||
const workerPath = path.join(tempDir, 'worker.js');
|
||||
writeReadyWorker(
|
||||
workerPath,
|
||||
`
|
||||
const fs = require('node:fs');
|
||||
const { parentPort } = require('node:worker_threads');
|
||||
const markerPath = ${JSON.stringify(markerPath)};
|
||||
let current = [];
|
||||
parentPort.on('message', (msg) => {
|
||||
if (msg && msg.type === 'sub-batch') {
|
||||
current = msg.files.map((f) => f.path);
|
||||
if (!fs.existsSync(markerPath)) {
|
||||
fs.writeFileSync(markerPath, 'throw once');
|
||||
parentPort.postMessage({ type: 'starting-file', path: current[0] });
|
||||
// Uncaught throw — Node Worker emits an 'error' event.
|
||||
throw new Error('simulated native error');
|
||||
}
|
||||
parentPort.postMessage({ type: 'progress', filesProcessed: current.length });
|
||||
parentPort.postMessage({ type: 'sub-batch-done' });
|
||||
return;
|
||||
}
|
||||
if (msg && msg.type === 'flush') {
|
||||
parentPort.postMessage({ type: 'result', data: { paths: current } });
|
||||
}
|
||||
});
|
||||
`,
|
||||
);
|
||||
|
||||
pool = createWorkerPool(pathToFileURL(workerPath) as URL, 1, {
|
||||
subBatchIdleTimeoutMs: 2000,
|
||||
consecutiveFailureThreshold: 5,
|
||||
maxRespawnsPerSlot: 3,
|
||||
});
|
||||
|
||||
try {
|
||||
const results = await pool.dispatch<{ path: string; content: string }, { paths: string[] }>([
|
||||
{ path: 'thrown.ts', content: '' },
|
||||
{ path: 'recovered.ts', content: '' },
|
||||
]);
|
||||
expect(results.length).toBe(1);
|
||||
expect(results[0].paths).toEqual(['recovered.ts']);
|
||||
expect(pool.getQuarantinedPaths?.() ?? []).toEqual(['thrown.ts']);
|
||||
} finally {
|
||||
fs.rmSync(tempDir, { recursive: true, force: true });
|
||||
}
|
||||
});
|
||||
});
|
||||
|
|
|
|||
|
|
@ -1,16 +1,21 @@
|
|||
import { beforeEach, describe, expect, it, vi } from 'vitest';
|
||||
|
||||
const { runFullAnalysisMock, generateAIContextFilesMock, generateSkillFilesMock } = vi.hoisted(
|
||||
() => {
|
||||
const { runFullAnalysisMock, generateAIContextFilesMock, generateSkillFilesMock, cliErrorMock } =
|
||||
vi.hoisted(() => {
|
||||
const runFullAnalysisMock = vi.fn();
|
||||
const generateAIContextFilesMock = vi.fn(async () => ({ files: [] as string[] }));
|
||||
const generateSkillFilesMock = vi.fn(async () => ({
|
||||
skills: [{ name: 'c', label: 'Community', symbolCount: 1, fileCount: 1 }],
|
||||
outputPath: '/repo/.claude/skills/generated',
|
||||
}));
|
||||
return { runFullAnalysisMock, generateAIContextFilesMock, generateSkillFilesMock };
|
||||
},
|
||||
);
|
||||
const cliErrorMock = vi.fn();
|
||||
return {
|
||||
runFullAnalysisMock,
|
||||
generateAIContextFilesMock,
|
||||
generateSkillFilesMock,
|
||||
cliErrorMock,
|
||||
};
|
||||
});
|
||||
|
||||
vi.mock('../../src/core/run-analyze.js', () => ({
|
||||
runFullAnalysis: runFullAnalysisMock,
|
||||
|
|
@ -24,6 +29,10 @@ vi.mock('../../src/cli/skill-gen.js', () => ({
|
|||
generateSkillFiles: generateSkillFilesMock,
|
||||
}));
|
||||
|
||||
vi.mock('../../src/cli/cli-message.js', () => ({
|
||||
cliError: cliErrorMock,
|
||||
}));
|
||||
|
||||
vi.mock('../../src/core/lbug/lbug-adapter.js', () => ({
|
||||
closeLbug: vi.fn(async () => undefined),
|
||||
}));
|
||||
|
|
@ -62,6 +71,7 @@ describe('analyzeCommand commander → runFullAnalysis noStats bridge (#1477)',
|
|||
skills: [{ name: 'c', label: 'Community', symbolCount: 1, fileCount: 1 }],
|
||||
outputPath: '/repo/.claude/skills/generated',
|
||||
});
|
||||
cliErrorMock.mockReset();
|
||||
process.exitCode = undefined;
|
||||
process.env.NODE_OPTIONS = `${process.env.NODE_OPTIONS ?? ''} --max-old-space-size=8192`.trim();
|
||||
});
|
||||
|
|
@ -104,6 +114,27 @@ describe('analyzeCommand commander → runFullAnalysis noStats bridge (#1477)',
|
|||
expect(opts.skipAgentsMd).toBe(true);
|
||||
});
|
||||
|
||||
it('passes --repair-fts through to runFullAnalysis', async () => {
|
||||
const { analyzeCommand } = await import('../../src/cli/analyze.js');
|
||||
|
||||
await analyzeCommand(undefined, { repairFts: true });
|
||||
|
||||
const opts = runFullAnalysisMock.mock.calls[0][1];
|
||||
expect(opts.repairFts).toBe(true);
|
||||
});
|
||||
|
||||
it('rejects combining --repair-fts with --force', async () => {
|
||||
const { analyzeCommand } = await import('../../src/cli/analyze.js');
|
||||
|
||||
await analyzeCommand(undefined, { repairFts: true, force: true });
|
||||
|
||||
expect(process.exitCode).toBe(1);
|
||||
expect(cliErrorMock).toHaveBeenCalledWith(
|
||||
expect.stringMatching(/cannot combine `--repair-fts` with `--force`/i),
|
||||
);
|
||||
expect(runFullAnalysisMock).not.toHaveBeenCalled();
|
||||
});
|
||||
|
||||
it('passes stats:false as noStats to generateAIContextFiles on the --skills regeneration path (#1477)', async () => {
|
||||
runFullAnalysisMock.mockResolvedValueOnce({
|
||||
repoName: 'repo',
|
||||
|
|
|
|||
140
gitnexus/test/unit/analyze-worker-pool-size.test.ts
Normal file
140
gitnexus/test/unit/analyze-worker-pool-size.test.ts
Normal file
|
|
@ -0,0 +1,140 @@
|
|||
import { afterEach, beforeEach, describe, expect, it, vi } from 'vitest';
|
||||
|
||||
const runFullAnalysisMock = vi.fn();
|
||||
|
||||
vi.mock('../../src/core/run-analyze.js', () => ({
|
||||
runFullAnalysis: runFullAnalysisMock,
|
||||
}));
|
||||
|
||||
vi.mock('../../src/core/lbug/lbug-adapter.js', () => ({
|
||||
closeLbug: vi.fn(async () => undefined),
|
||||
}));
|
||||
|
||||
vi.mock('../../src/storage/repo-manager.js', () => ({
|
||||
getStoragePaths: vi.fn(() => ({ storagePath: '.gitnexus', lbugPath: '.gitnexus/lbug' })),
|
||||
getGlobalRegistryPath: vi.fn(() => 'registry.json'),
|
||||
RegistryNameCollisionError: class RegistryNameCollisionError extends Error {},
|
||||
AnalysisNotFinalizedError: class AnalysisNotFinalizedError extends Error {},
|
||||
assertAnalysisFinalized: vi.fn(async () => undefined),
|
||||
}));
|
||||
|
||||
vi.mock('../../src/storage/git.js', () => ({
|
||||
getGitRoot: vi.fn(() => '/repo'),
|
||||
hasGitDir: vi.fn(() => true),
|
||||
}));
|
||||
|
||||
vi.mock('../../src/core/ingestion/utils/max-file-size.js', () => ({
|
||||
getMaxFileSizeBannerMessage: vi.fn(() => null),
|
||||
}));
|
||||
|
||||
describe('analyzeCommand --workers validation', () => {
|
||||
// Capture the host's NODE_OPTIONS once so afterEach can restore it cleanly,
|
||||
// and the env-leak regression test below has a stable baseline. Without
|
||||
// afterEach, beforeEach's `process.env.NODE_OPTIONS = ...` accumulated
|
||||
// `--max-old-space-size=8192` tokens across runs (L4 from PR #1693 review).
|
||||
const ORIGINAL_NODE_OPTIONS = process.env.NODE_OPTIONS;
|
||||
|
||||
beforeEach(() => {
|
||||
vi.resetModules();
|
||||
runFullAnalysisMock.mockReset();
|
||||
process.exitCode = undefined;
|
||||
process.env.NODE_OPTIONS = `${process.env.NODE_OPTIONS ?? ''} --max-old-space-size=8192`.trim();
|
||||
});
|
||||
|
||||
afterEach(() => {
|
||||
if (ORIGINAL_NODE_OPTIONS === undefined) {
|
||||
delete process.env.NODE_OPTIONS;
|
||||
} else {
|
||||
process.env.NODE_OPTIONS = ORIGINAL_NODE_OPTIONS;
|
||||
}
|
||||
});
|
||||
|
||||
it.each(['abc', '-5', '1.5', 'Infinity', 'NaN'])(
|
||||
'rejects invalid --workers value %s before analysis starts',
|
||||
async (workers) => {
|
||||
const { _captureLogger } = await import('../../src/core/logger.js');
|
||||
const cap = _captureLogger();
|
||||
const { analyzeCommand } = await import('../../src/cli/analyze.js');
|
||||
|
||||
await analyzeCommand(undefined, { workers });
|
||||
|
||||
expect(process.exitCode).toBe(1);
|
||||
expect(
|
||||
cap
|
||||
.records()
|
||||
.some((r) =>
|
||||
String(r.msg ?? '').startsWith(' --workers must be a non-negative integer'),
|
||||
),
|
||||
).toBe(true);
|
||||
expect(runFullAnalysisMock).not.toHaveBeenCalled();
|
||||
cap.restore();
|
||||
},
|
||||
);
|
||||
|
||||
it('threads --workers through runFullAnalysis options as workerPoolSize', async () => {
|
||||
const { analyzeCommand } = await import('../../src/cli/analyze.js');
|
||||
runFullAnalysisMock.mockResolvedValue({
|
||||
repoName: 'repo',
|
||||
repoPath: '/repo',
|
||||
stats: {},
|
||||
alreadyUpToDate: true,
|
||||
});
|
||||
|
||||
await analyzeCommand(undefined, { workers: '12' });
|
||||
|
||||
expect(runFullAnalysisMock).toHaveBeenCalledWith(
|
||||
expect.any(String),
|
||||
expect.objectContaining({ workerPoolSize: 12 }),
|
||||
expect.any(Object),
|
||||
);
|
||||
});
|
||||
|
||||
it('threads --workers 0 as workerPoolSize: 0 (sequential-fallback signal)', async () => {
|
||||
const { analyzeCommand } = await import('../../src/cli/analyze.js');
|
||||
runFullAnalysisMock.mockResolvedValue({
|
||||
repoName: 'repo',
|
||||
repoPath: '/repo',
|
||||
stats: {},
|
||||
alreadyUpToDate: true,
|
||||
});
|
||||
|
||||
await analyzeCommand(undefined, { workers: '0' });
|
||||
|
||||
expect(runFullAnalysisMock).toHaveBeenCalledWith(
|
||||
expect.any(String),
|
||||
expect.objectContaining({ workerPoolSize: 0 }),
|
||||
expect.any(Object),
|
||||
);
|
||||
expect(process.exitCode).toBeUndefined();
|
||||
});
|
||||
|
||||
it('does not mutate GITNEXUS_WORKER_POOL_SIZE in process.env', async () => {
|
||||
const { analyzeCommand } = await import('../../src/cli/analyze.js');
|
||||
runFullAnalysisMock.mockResolvedValue({
|
||||
repoName: 'repo',
|
||||
repoPath: '/repo',
|
||||
stats: {},
|
||||
alreadyUpToDate: true,
|
||||
});
|
||||
|
||||
const before = process.env.GITNEXUS_WORKER_POOL_SIZE;
|
||||
await analyzeCommand(undefined, { workers: '7' });
|
||||
expect(process.env.GITNEXUS_WORKER_POOL_SIZE).toBe(before);
|
||||
});
|
||||
|
||||
it('restores snapshotted env vars after returning (no cross-invocation leak)', async () => {
|
||||
const { analyzeCommand } = await import('../../src/cli/analyze.js');
|
||||
runFullAnalysisMock.mockResolvedValue({
|
||||
repoName: 'repo',
|
||||
repoPath: '/repo',
|
||||
stats: {},
|
||||
alreadyUpToDate: true,
|
||||
});
|
||||
|
||||
const originalVerbose = process.env.GITNEXUS_VERBOSE;
|
||||
const originalMaxFileSize = process.env.GITNEXUS_MAX_FILE_SIZE;
|
||||
await analyzeCommand(undefined, { verbose: true, maxFileSize: '1024' });
|
||||
expect(process.env.GITNEXUS_VERBOSE).toBe(originalVerbose);
|
||||
expect(process.env.GITNEXUS_MAX_FILE_SIZE).toBe(originalMaxFileSize);
|
||||
});
|
||||
});
|
||||
|
|
@ -1,4 +1,4 @@
|
|||
import { beforeEach, describe, expect, it, vi } from 'vitest';
|
||||
import { afterEach, beforeEach, describe, expect, it, vi } from 'vitest';
|
||||
|
||||
const runFullAnalysisMock = vi.fn();
|
||||
|
||||
|
|
@ -28,12 +28,26 @@ vi.mock('../../src/core/ingestion/utils/max-file-size.js', () => ({
|
|||
}));
|
||||
|
||||
describe('analyzeCommand worker timeout validation', () => {
|
||||
// analyzeCommand now snapshot/restores GITNEXUS_* env vars, so the value
|
||||
// observed *after* the call is the pre-call baseline — not what the CLI
|
||||
// wrote. Tests that need to verify "the env was set for the downstream
|
||||
// call" must capture it inside the runFullAnalysisMock implementation.
|
||||
const ORIGINAL_TIMEOUT = process.env.GITNEXUS_WORKER_SUB_BATCH_TIMEOUT_MS;
|
||||
const ORIGINAL_NODE_OPTIONS = process.env.NODE_OPTIONS;
|
||||
|
||||
beforeEach(() => {
|
||||
vi.resetModules();
|
||||
runFullAnalysisMock.mockReset();
|
||||
process.exitCode = undefined;
|
||||
process.env.NODE_OPTIONS = `${process.env.NODE_OPTIONS ?? ''} --max-old-space-size=8192`.trim();
|
||||
delete process.env.GITNEXUS_WORKER_SUB_BATCH_TIMEOUT_MS;
|
||||
});
|
||||
|
||||
afterEach(() => {
|
||||
if (ORIGINAL_NODE_OPTIONS === undefined) {
|
||||
delete process.env.NODE_OPTIONS;
|
||||
} else {
|
||||
process.env.NODE_OPTIONS = ORIGINAL_NODE_OPTIONS;
|
||||
}
|
||||
});
|
||||
|
||||
it.each(['0', 'abc', '-5', 'Infinity'])(
|
||||
|
|
@ -56,18 +70,28 @@ describe('analyzeCommand worker timeout validation', () => {
|
|||
},
|
||||
);
|
||||
|
||||
it('sets the worker timeout environment variable for valid values', async () => {
|
||||
it('sets the worker timeout env var during the runFullAnalysis call and restores it after', async () => {
|
||||
const { analyzeCommand } = await import('../../src/cli/analyze.js');
|
||||
runFullAnalysisMock.mockResolvedValue({
|
||||
repoName: 'repo',
|
||||
repoPath: '/repo',
|
||||
stats: {},
|
||||
alreadyUpToDate: true,
|
||||
let envAtCallTime: string | undefined;
|
||||
runFullAnalysisMock.mockImplementation(async () => {
|
||||
envAtCallTime = process.env.GITNEXUS_WORKER_SUB_BATCH_TIMEOUT_MS;
|
||||
return {
|
||||
repoName: 'repo',
|
||||
repoPath: '/repo',
|
||||
stats: {},
|
||||
alreadyUpToDate: true,
|
||||
};
|
||||
});
|
||||
|
||||
await analyzeCommand(undefined, { workerTimeout: '2' });
|
||||
|
||||
expect(process.env.GITNEXUS_WORKER_SUB_BATCH_TIMEOUT_MS).toBe('2000');
|
||||
// Downstream sees the parsed milliseconds value during the call.
|
||||
expect(envAtCallTime).toBe('2000');
|
||||
expect(runFullAnalysisMock).toHaveBeenCalled();
|
||||
// After the call, the snapshot/restore wrapper has reset the env so a
|
||||
// subsequent analyzeCommand invocation in the same host (or test
|
||||
// process) doesn't inherit the previous call's worker timeout. This
|
||||
// is the env-leak fix from PR #1693 review (B2).
|
||||
expect(process.env.GITNEXUS_WORKER_SUB_BATCH_TIMEOUT_MS).toBe(ORIGINAL_TIMEOUT);
|
||||
});
|
||||
});
|
||||
|
|
|
|||
60
gitnexus/test/unit/api-readonly-wiring.test.ts
Normal file
60
gitnexus/test/unit/api-readonly-wiring.test.ts
Normal file
|
|
@ -0,0 +1,60 @@
|
|||
import { describe, expect, it } from 'vitest';
|
||||
import fs from 'node:fs/promises';
|
||||
import path from 'node:path';
|
||||
|
||||
/**
|
||||
* Regression guard for issue: "Cannot open file ... lbug.shadow - Error 2"
|
||||
*
|
||||
* Read-only HTTP endpoints (graph, search, grep) must open the LadybugDB with
|
||||
* `{ readOnly: true }` so the engine never engages the checkpoint machinery
|
||||
* (`.shadow` sidecar). Write-mode opens for read-only operations were the
|
||||
* trigger for the Windows-only "Cannot open file ... lbug.shadow" failures
|
||||
* observed in E2E runs.
|
||||
*
|
||||
* If you add another read-only endpoint and forget the option, this file
|
||||
* fails — keeping the contract explicit at the static-analysis layer.
|
||||
*
|
||||
* Companion: api-query-readonly-wiring.test.ts (covers /api/query).
|
||||
* Precedent: PR #1655 set the pattern for /api/query.
|
||||
*/
|
||||
describe('api read-only endpoint wiring', () => {
|
||||
const readSource = () =>
|
||||
fs.readFile(path.join(__dirname, '..', '..', 'src', 'server', 'api.ts'), 'utf-8');
|
||||
|
||||
it('/api/graph stream path opens read-only', async () => {
|
||||
const source = await readSource();
|
||||
expect(source).toMatch(
|
||||
/streamGraphNdjson\(res, includeContent, abortController\.signal\)[\s\S]{0,200}readOnly:\s*true/,
|
||||
);
|
||||
});
|
||||
|
||||
it('/api/graph non-stream path opens read-only', async () => {
|
||||
const source = await readSource();
|
||||
expect(source).toMatch(/buildGraph\(includeContent\)[\s\S]{0,80}readOnly:\s*true/);
|
||||
});
|
||||
|
||||
it('/api/search opens read-only', async () => {
|
||||
const source = await readSource();
|
||||
// The /api/search handler ends its withLbugDb callback with
|
||||
// `return { searchResults: enriched, ftsAvailable };` immediately before
|
||||
// the closing brace + options object. Match that suffix to confirm the
|
||||
// search call site, not /api/query.
|
||||
expect(source).toMatch(/searchResults: enriched, ftsAvailable[\s\S]{0,80}readOnly:\s*true/);
|
||||
});
|
||||
|
||||
it('/api/grep opens read-only', async () => {
|
||||
const source = await readSource();
|
||||
expect(source).toMatch(/MATCH \(n:File\)[\s\S]{0,300}readOnly:\s*true/);
|
||||
});
|
||||
|
||||
it('/api/embed remains write-mode (writes embeddings — must not be flipped to readOnly)', async () => {
|
||||
const source = await readSource();
|
||||
// Negative assertion: no `readOnly: true` between the embed job's
|
||||
// `runEmbeddingPipeline` call site and its withLbugDb open. Embed writes
|
||||
// back vector rows; flipping this to readOnly would silently break it.
|
||||
const embedSection = source.match(/runEmbeddingPipeline[\s\S]{0,400}\}\s*\)\s*;[\s\S]{0,200}/);
|
||||
if (embedSection) {
|
||||
expect(embedSection[0]).not.toMatch(/readOnly:\s*true/);
|
||||
}
|
||||
});
|
||||
});
|
||||
|
|
@ -40,6 +40,31 @@ describe('BM25 search', () => {
|
|||
['Interface', 'interface_fts', ['name', 'content']],
|
||||
]);
|
||||
});
|
||||
|
||||
it('verifies all configured FTS indexes are queryable', async () => {
|
||||
const executeQuery = vi.fn().mockResolvedValue([]);
|
||||
const { verifySearchFTSIndexes } = await import('../../src/core/search/fts-indexes.js');
|
||||
|
||||
const missing = await verifySearchFTSIndexes(executeQuery);
|
||||
|
||||
expect(missing).toEqual([]);
|
||||
expect(executeQuery).toHaveBeenCalledTimes(5);
|
||||
});
|
||||
|
||||
it('reports missing indexes when an FTS probe fails', async () => {
|
||||
const executeQuery = vi
|
||||
.fn()
|
||||
.mockResolvedValueOnce([])
|
||||
.mockRejectedValueOnce(new Error('index does not exist'))
|
||||
.mockResolvedValueOnce([])
|
||||
.mockResolvedValueOnce([])
|
||||
.mockResolvedValueOnce([]);
|
||||
const { verifySearchFTSIndexes } = await import('../../src/core/search/fts-indexes.js');
|
||||
|
||||
const missing = await verifySearchFTSIndexes(executeQuery);
|
||||
|
||||
expect(missing).toEqual(['Function.function_fts']);
|
||||
});
|
||||
});
|
||||
|
||||
describe('searchFTSFromLbug', () => {
|
||||
|
|
|
|||
|
|
@ -203,7 +203,7 @@ describe('LocalBackend.callTool', () => {
|
|||
const result = await backend.callTool('query', { query: 'ProcessActivity' });
|
||||
|
||||
expect(result).toHaveProperty('warning');
|
||||
expect((result as any).warning).toMatch(/gitnexus analyze --force/);
|
||||
expect((result as any).warning).toMatch(/gitnexus analyze --repair-fts/);
|
||||
});
|
||||
|
||||
it('does not include warning when ftsAvailable is true with zero results', async () => {
|
||||
|
|
|
|||
|
|
@ -76,4 +76,11 @@ describe('CLI help surface', () => {
|
|||
expect(result.stdout).toContain('understand-quickly');
|
||||
expect(result.stdout).toContain('UNDERSTAND_QUICKLY_TOKEN');
|
||||
});
|
||||
|
||||
it('analyze help includes the FTS repair option', () => {
|
||||
const result = runHelp('analyze');
|
||||
|
||||
expect(result.status).toBe(0);
|
||||
expect(result.stdout).toContain('--repair-fts');
|
||||
});
|
||||
});
|
||||
|
|
|
|||
|
|
@ -189,6 +189,81 @@ describe('resolveWorktreeCwd — auto-detection helper', () => {
|
|||
rmSync(repoB, { recursive: true, force: true });
|
||||
}
|
||||
});
|
||||
|
||||
it('returns worktreeDir unchanged when repoPath IS a linked worktree and launchCwd is the main checkout', () => {
|
||||
// Regression for: detect_changes returns no changes when the MCP server
|
||||
// runs from the main checkout but the resolved repo index is a separately-
|
||||
// indexed linked worktree (issue #1659 / dpearson2699 report).
|
||||
//
|
||||
// Before the fix, resolveWorktreeCwd would detect that launchCwd (main
|
||||
// checkout) and repoPath (worktree) share the same canonical root and
|
||||
// wrongly override repoPath with the main-checkout path, causing git diff
|
||||
// to run from the wrong directory and return 0 changes.
|
||||
const repoDir = mkdtempSync(path.join(os.tmpdir(), 'gitnexus-rwc-idx-wt-'));
|
||||
try {
|
||||
execSync('git init -q', { cwd: repoDir, stdio: 'ignore' });
|
||||
execSync('git config user.email "test@example.com"', { cwd: repoDir, stdio: 'ignore' });
|
||||
execSync('git config user.name "Test"', { cwd: repoDir, stdio: 'ignore' });
|
||||
writeFileSync(path.join(repoDir, 'x.ts'), 'export const x = 1;\n');
|
||||
execSync('git add x.ts', { cwd: repoDir, stdio: 'ignore' });
|
||||
execSync('git commit -q -m "initial"', { cwd: repoDir, stdio: 'ignore' });
|
||||
|
||||
const worktreeDir = path.join(repoDir, 'wt-indexed');
|
||||
execSync(`git worktree add -q -b indexed "${worktreeDir}"`, {
|
||||
cwd: repoDir,
|
||||
stdio: 'ignore',
|
||||
});
|
||||
|
||||
// Simulate: repo registry entry points to the worktree (repoPath = worktreeDir)
|
||||
// but the MCP server was launched from the main checkout (launchCwd = repoDir).
|
||||
// resolveWorktreeCwd must NOT override the correct worktree path with repoDir.
|
||||
const result = resolveWorktreeCwd(worktreeDir, repoDir);
|
||||
expect(realpathSync.native(result)).toBe(realpathSync.native(worktreeDir));
|
||||
expect(realpathSync.native(result)).not.toBe(realpathSync.native(repoDir));
|
||||
} finally {
|
||||
try {
|
||||
execSync('git worktree remove -f wt-indexed', { cwd: repoDir, stdio: 'ignore' });
|
||||
} catch {
|
||||
// ignore
|
||||
}
|
||||
rmSync(repoDir, { recursive: true, force: true });
|
||||
}
|
||||
});
|
||||
|
||||
it('returns worktreeA unchanged when both repoPath and launchCwd are different linked worktrees of the same repo', () => {
|
||||
// Covers: repoPath = wt-A (indexed), launchCwd = wt-B (server launched from another worktree).
|
||||
// The guard fires on repoPath being a linked worktree regardless of what launchCwd is,
|
||||
// so wt-A must be returned unchanged — not wt-B, not the main checkout.
|
||||
const repoDir = mkdtempSync(path.join(os.tmpdir(), 'gitnexus-rwc-two-wt-'));
|
||||
try {
|
||||
execSync('git init -q', { cwd: repoDir, stdio: 'ignore' });
|
||||
execSync('git config user.email "test@example.com"', { cwd: repoDir, stdio: 'ignore' });
|
||||
execSync('git config user.name "Test"', { cwd: repoDir, stdio: 'ignore' });
|
||||
writeFileSync(path.join(repoDir, 'x.ts'), 'export const x = 1;\n');
|
||||
execSync('git add x.ts', { cwd: repoDir, stdio: 'ignore' });
|
||||
execSync('git commit -q -m "initial"', { cwd: repoDir, stdio: 'ignore' });
|
||||
|
||||
const worktreeA = path.join(repoDir, 'wt-a');
|
||||
const worktreeB = path.join(repoDir, 'wt-b');
|
||||
execSync(`git worktree add -q -b branch-a "${worktreeA}"`, { cwd: repoDir, stdio: 'ignore' });
|
||||
execSync(`git worktree add -q -b branch-b "${worktreeB}"`, { cwd: repoDir, stdio: 'ignore' });
|
||||
|
||||
// repoPath = wt-A (the indexed worktree), launchCwd = wt-B (where the server runs).
|
||||
// resolveWorktreeCwd must return wt-A — the indexed path — unchanged.
|
||||
const result = resolveWorktreeCwd(worktreeA, worktreeB);
|
||||
expect(realpathSync.native(result)).toBe(realpathSync.native(worktreeA));
|
||||
expect(realpathSync.native(result)).not.toBe(realpathSync.native(worktreeB));
|
||||
expect(realpathSync.native(result)).not.toBe(realpathSync.native(repoDir));
|
||||
} finally {
|
||||
try {
|
||||
execSync('git worktree remove -f wt-a', { cwd: repoDir, stdio: 'ignore' });
|
||||
execSync('git worktree remove -f wt-b', { cwd: repoDir, stdio: 'ignore' });
|
||||
} catch {
|
||||
// ignore
|
||||
}
|
||||
rmSync(repoDir, { recursive: true, force: true });
|
||||
}
|
||||
});
|
||||
});
|
||||
|
||||
// ── Guard logic via real path arithmetic ─────────────────────────────────────
|
||||
|
|
|
|||
|
|
@ -19,8 +19,8 @@ import {
|
|||
// ─── validateHost ────────────────────────────────────────────────────
|
||||
|
||||
describe('validateHost', () => {
|
||||
it('normalizes "localhost" to "127.0.0.1"', () => {
|
||||
expect(validateHost('localhost')).toBe('127.0.0.1');
|
||||
it('passes "localhost" through unchanged', () => {
|
||||
expect(validateHost('localhost')).toBe('localhost');
|
||||
});
|
||||
|
||||
it('accepts valid IPv4 addresses', () => {
|
||||
|
|
|
|||
|
|
@ -92,6 +92,77 @@ public class UserController {
|
|||
expect(getRoute!.confidence).toBe(0.9);
|
||||
expect(getRoute!.symbolUid).not.toBe('file-uid-ctrl');
|
||||
});
|
||||
|
||||
it('supplements graph providers with source-scan providers from other files', async () => {
|
||||
const dir = path.join(tmpDir, 'graph-source-provider-union');
|
||||
fs.mkdirSync(path.join(dir, 'src/controller'), { recursive: true });
|
||||
fs.mkdirSync(path.join(dir, 'cmd'), { recursive: true });
|
||||
fs.writeFileSync(
|
||||
path.join(dir, 'src/controller/UserController.java'),
|
||||
`
|
||||
@RestController
|
||||
@RequestMapping("/api/v2")
|
||||
public class UserController {
|
||||
@GetMapping("/users")
|
||||
public List<User> list() { return service.findAll(); }
|
||||
}
|
||||
`,
|
||||
);
|
||||
fs.writeFileSync(
|
||||
path.join(dir, 'cmd/server.go'),
|
||||
`
|
||||
package main
|
||||
|
||||
func healthHandler(w http.ResponseWriter, r *http.Request) {}
|
||||
|
||||
func main() {
|
||||
http.HandleFunc("/api/health", healthHandler)
|
||||
}
|
||||
`,
|
||||
);
|
||||
|
||||
const mockDbExecutor = async (query: string) => {
|
||||
if (query.includes('HANDLES_ROUTE')) {
|
||||
return [
|
||||
{
|
||||
fileId: 'file-uid-ctrl',
|
||||
filePath: 'src/controller/UserController.java',
|
||||
routePath: '/api/v2/users',
|
||||
routeId: 'route-uid-users',
|
||||
responseKeys: null,
|
||||
routeSource: 'decorator-GetMapping',
|
||||
},
|
||||
];
|
||||
}
|
||||
if (query.includes('FETCHES')) return [];
|
||||
if (query.includes('CONTAINS')) {
|
||||
return [
|
||||
{
|
||||
uid: 'uid-ctrl-list',
|
||||
name: 'list',
|
||||
filePath: 'src/controller/UserController.java',
|
||||
labels: ['Method'],
|
||||
},
|
||||
];
|
||||
}
|
||||
return [];
|
||||
};
|
||||
|
||||
const contracts = await extractor.extract(mockDbExecutor, dir, makeRepo(dir));
|
||||
const providers = contracts.filter((c) => c.role === 'provider');
|
||||
|
||||
const graphRouteMatches = providers.filter(
|
||||
(c) => c.contractId === 'http::GET::/api/v2/users',
|
||||
);
|
||||
expect(graphRouteMatches).toHaveLength(1);
|
||||
expect(graphRouteMatches[0].symbolUid).toBe('uid-ctrl-list');
|
||||
expect(graphRouteMatches[0].meta.extractionStrategy).toBe('graph_assisted');
|
||||
|
||||
const sourceRoute = providers.find((c) => c.contractId === 'http::GET::/api/health');
|
||||
expect(sourceRoute).toBeDefined();
|
||||
expect(sourceRoute?.symbolName).toBe('healthHandler');
|
||||
expect(sourceRoute?.meta.extractionStrategy).toBe('source_scan');
|
||||
});
|
||||
});
|
||||
|
||||
describe('provider extraction — source-scan fallback (Strategy B)', () => {
|
||||
|
|
@ -166,6 +237,30 @@ export default router;
|
|||
).toBeDefined();
|
||||
});
|
||||
|
||||
it('dedupes source-only providers by contract id', async () => {
|
||||
const dir = path.join(tmpDir, 'source-only-same-contract-id');
|
||||
fs.mkdirSync(path.join(dir, 'src/routes'), { recursive: true });
|
||||
fs.writeFileSync(
|
||||
path.join(dir, 'src/routes/health-a.ts'),
|
||||
`
|
||||
router.get('/api/health', healthA);
|
||||
`,
|
||||
);
|
||||
fs.writeFileSync(
|
||||
path.join(dir, 'src/routes/health-b.ts'),
|
||||
`
|
||||
router.get('/api/health', healthB);
|
||||
`,
|
||||
);
|
||||
|
||||
const contracts = await extractor.extract(null, dir, makeRepo(dir));
|
||||
const providers = contracts.filter((c) => c.contractId === 'http::GET::/api/health');
|
||||
|
||||
expect(providers).toHaveLength(1);
|
||||
expect(providers[0].role).toBe('provider');
|
||||
expect(providers[0].meta.extractionStrategy).toBe('source_scan');
|
||||
});
|
||||
|
||||
it('extracts Go Gin and Echo route registrations', async () => {
|
||||
const dir = path.join(tmpDir, 'go-frameworks');
|
||||
fs.mkdirSync(path.join(dir, 'cmd'), { recursive: true });
|
||||
|
|
@ -740,6 +835,59 @@ async def create_user(user: UserCreate):
|
|||
expect(consumers[0].confidence).toBe(0.9);
|
||||
expect(consumers[0].symbolName).toBe('fetchUsers');
|
||||
});
|
||||
|
||||
it('supplements graph consumers with source-scan consumers from other files', async () => {
|
||||
const dir = path.join(tmpDir, 'graph-source-consumer-union');
|
||||
fs.mkdirSync(path.join(dir, 'src/api'), { recursive: true });
|
||||
fs.writeFileSync(path.join(dir, 'src/api/graph.ts'), 'export const api = {};');
|
||||
fs.writeFileSync(
|
||||
path.join(dir, 'src/api/health.ts'),
|
||||
`
|
||||
export async function fetchHealth() {
|
||||
const res = await fetch('/api/health');
|
||||
return res.json();
|
||||
}
|
||||
`,
|
||||
);
|
||||
|
||||
const mockDbExecutor = async (query: string) => {
|
||||
if (query.includes('HANDLES_ROUTE')) return [];
|
||||
if (query.includes('FETCHES')) {
|
||||
return [
|
||||
{
|
||||
fileId: 'file-uid-api',
|
||||
filePath: 'src/api/graph.ts',
|
||||
routePath: '/api/users',
|
||||
routeId: 'route-uid-users',
|
||||
fetchReason: 'fetch-url-match',
|
||||
},
|
||||
];
|
||||
}
|
||||
if (query.includes('CONTAINS')) {
|
||||
return [
|
||||
{
|
||||
uid: 'uid-fn-fetch',
|
||||
name: 'fetchUsers',
|
||||
filePath: 'src/api/graph.ts',
|
||||
labels: ['Function'],
|
||||
},
|
||||
];
|
||||
}
|
||||
return [];
|
||||
};
|
||||
|
||||
const contracts = await extractor.extract(mockDbExecutor, dir, makeRepo(dir));
|
||||
const consumers = contracts.filter((c) => c.role === 'consumer');
|
||||
|
||||
const graphConsumer = consumers.find((c) => c.contractId === 'http::GET::/api/users');
|
||||
expect(graphConsumer).toBeDefined();
|
||||
expect(graphConsumer?.symbolUid).toBe('uid-fn-fetch');
|
||||
expect(graphConsumer?.meta.extractionStrategy).toBe('graph_assisted');
|
||||
|
||||
const sourceConsumer = consumers.find((c) => c.contractId === 'http::GET::/api/health');
|
||||
expect(sourceConsumer).toBeDefined();
|
||||
expect(sourceConsumer?.meta.extractionStrategy).toBe('source_scan');
|
||||
});
|
||||
});
|
||||
|
||||
describe('edge cases', () => {
|
||||
|
|
|
|||
132
gitnexus/test/unit/lbug-pool-win-fts-probe.test.ts
Normal file
132
gitnexus/test/unit/lbug-pool-win-fts-probe.test.ts
Normal file
|
|
@ -0,0 +1,132 @@
|
|||
/**
|
||||
* Unit tests for the Windows FTS probe in pool-adapter.ts.
|
||||
*
|
||||
* Covers `hasLocalWinFtsExtension()` — the helper that gates the
|
||||
* Windows-only skip of `loadFTSExtension` in `doInitLbug` and
|
||||
* `initLbugWithDb`. Issue #1690 / PR #1692.
|
||||
*
|
||||
* The probe is exercised against a real temp filesystem with
|
||||
* `os.homedir()` spied to point at the tempdir. This tests the
|
||||
* actual fs surface (readdir/stat semantics, missing-dir behavior,
|
||||
* zero-byte file handling) rather than mocking fs internals.
|
||||
*
|
||||
* The Windows-branch conditional in `doInitLbug` / `initLbugWithDb`
|
||||
* is intentionally not unit-tested in isolation: those functions
|
||||
* require a fully constructed `lbug.Database` + `Connection` pool
|
||||
* and are exercised end-to-end by `test/integration/lbug-pool*.test.ts`
|
||||
* on the `windows-latest` matrix. The conditional itself is a single
|
||||
* expression — `(await hasLocalWinFtsExtension()) ? load : true` —
|
||||
* whose correctness reduces to the probe being correctly tested here.
|
||||
*/
|
||||
|
||||
import { afterEach, beforeEach, describe, expect, it, vi } from 'vitest';
|
||||
import os from 'os';
|
||||
import path from 'path';
|
||||
import fs from 'fs/promises';
|
||||
|
||||
// Stub out the LadybugDB native loader and its transitive importers so that
|
||||
// importing pool-adapter.ts in this unit test does not pull in the .node binary
|
||||
// (which is built by the postinstall script and is not always present in the
|
||||
// dev install used for unit tests).
|
||||
vi.mock('@ladybugdb/core', () => ({
|
||||
default: { Database: vi.fn(), Connection: vi.fn() },
|
||||
}));
|
||||
vi.mock('../../src/core/lbug/lbug-adapter.js', () => ({
|
||||
isReadOnlyDbError: vi.fn(() => false),
|
||||
loadFTSExtension: vi.fn(),
|
||||
}));
|
||||
vi.mock('../../src/core/lbug/lbug-config.js', () => ({
|
||||
createLbugDatabase: vi.fn(),
|
||||
isWalCorruptionError: vi.fn(() => false),
|
||||
WAL_RECOVERY_SUGGESTION: '',
|
||||
}));
|
||||
|
||||
import { hasLocalWinFtsExtension } from '../../src/core/lbug/pool-adapter.js';
|
||||
|
||||
describe('hasLocalWinFtsExtension', () => {
|
||||
let tmpHome: string;
|
||||
|
||||
beforeEach(async () => {
|
||||
tmpHome = await fs.mkdtemp(path.join(os.tmpdir(), 'gn-fts-probe-'));
|
||||
vi.spyOn(os, 'homedir').mockReturnValue(tmpHome);
|
||||
});
|
||||
|
||||
afterEach(async () => {
|
||||
vi.restoreAllMocks();
|
||||
await fs.rm(tmpHome, { recursive: true, force: true });
|
||||
});
|
||||
|
||||
it('returns false when ~/.lbdb/extension does not exist', async () => {
|
||||
// tmpHome is empty; the probe should swallow the readdir ENOENT and return false.
|
||||
await expect(hasLocalWinFtsExtension()).resolves.toBe(false);
|
||||
});
|
||||
|
||||
it('returns false when ~/.lbdb/extension exists but has no version dirs', async () => {
|
||||
await fs.mkdir(path.join(tmpHome, '.lbdb', 'extension'), { recursive: true });
|
||||
await expect(hasLocalWinFtsExtension()).resolves.toBe(false);
|
||||
});
|
||||
|
||||
it('returns true when a single version dir contains the FTS binary', async () => {
|
||||
const ftsDir = path.join(tmpHome, '.lbdb', 'extension', '0.16.0', 'win_amd64', 'fts');
|
||||
await fs.mkdir(ftsDir, { recursive: true });
|
||||
await fs.writeFile(path.join(ftsDir, 'libfts.lbug_extension'), Buffer.from('mock-binary'));
|
||||
await expect(hasLocalWinFtsExtension()).resolves.toBe(true);
|
||||
});
|
||||
|
||||
it('returns true when the binary is a zero-byte stub (LOAD failure handled downstream)', async () => {
|
||||
// Empirically verified in #1690 thread: LadybugDB resolves LOAD EXTENSION fts to a
|
||||
// version-specific path internally and the ExtensionManager's tryLoad try/catch
|
||||
// catches the resulting load error cleanly. Probe is intentionally generous here;
|
||||
// safety lives in the loader, not the probe.
|
||||
const ftsDir = path.join(tmpHome, '.lbdb', 'extension', '0.16.0', 'win_amd64', 'fts');
|
||||
await fs.mkdir(ftsDir, { recursive: true });
|
||||
await fs.writeFile(path.join(ftsDir, 'libfts.lbug_extension'), '');
|
||||
await expect(hasLocalWinFtsExtension()).resolves.toBe(true);
|
||||
});
|
||||
|
||||
it('returns true when multiple version dirs exist and only one carries the binary', async () => {
|
||||
const versions = ['0.15.0', '0.16.0', '0.17.0'];
|
||||
for (const v of versions) {
|
||||
await fs.mkdir(path.join(tmpHome, '.lbdb', 'extension', v, 'win_amd64', 'fts'), {
|
||||
recursive: true,
|
||||
});
|
||||
}
|
||||
// Only 0.16.0 has the binary; the probe should keep iterating past empty siblings.
|
||||
await fs.writeFile(
|
||||
path.join(
|
||||
tmpHome,
|
||||
'.lbdb',
|
||||
'extension',
|
||||
'0.16.0',
|
||||
'win_amd64',
|
||||
'fts',
|
||||
'libfts.lbug_extension',
|
||||
),
|
||||
Buffer.from('mock-binary'),
|
||||
);
|
||||
await expect(hasLocalWinFtsExtension()).resolves.toBe(true);
|
||||
});
|
||||
|
||||
it('returns false when version dirs exist but none contain the binary', async () => {
|
||||
// Adversarial topology raised by #1690 review: tree exists (Nix store, Bazel
|
||||
// sandbox seeding, corporate MDM-prepopulated user dirs) but the actual
|
||||
// libfts.lbug_extension file is absent. Probe must distinguish file from dir.
|
||||
const versions = ['0.15.0', '0.16.0', '0.17.0'];
|
||||
for (const v of versions) {
|
||||
await fs.mkdir(path.join(tmpHome, '.lbdb', 'extension', v, 'win_amd64', 'fts'), {
|
||||
recursive: true,
|
||||
});
|
||||
}
|
||||
await expect(hasLocalWinFtsExtension()).resolves.toBe(false);
|
||||
});
|
||||
|
||||
it('returns false when fs.readdir throws (e.g. permission denied on the extension root)', async () => {
|
||||
// Cover the outer try/catch — any fs error walking the extension root is
|
||||
// treated as "no binary present", matching the upstream skip-guard intent.
|
||||
const eaccess = Object.assign(new Error('EACCES: permission denied'), {
|
||||
code: 'EACCES',
|
||||
}) as NodeJS.ErrnoException;
|
||||
vi.spyOn(fs, 'readdir').mockRejectedValue(eaccess);
|
||||
await expect(hasLocalWinFtsExtension()).resolves.toBe(false);
|
||||
});
|
||||
});
|
||||
131
gitnexus/test/unit/parse-impl-chunk-concurrency.test.ts
Normal file
131
gitnexus/test/unit/parse-impl-chunk-concurrency.test.ts
Normal file
|
|
@ -0,0 +1,131 @@
|
|||
/**
|
||||
* U1 — Bounded chunk concurrency (B1 from PR #1693 review).
|
||||
*
|
||||
* Verifies that the new `parseChunkConcurrency` PipelineOption (and the
|
||||
* paired `GITNEXUS_PARSE_CHUNK_CONCURRENCY` env-var fallback) flow through
|
||||
* `runChunkedParseAndResolve` without changing graph output. Pre-fetching
|
||||
* chunk file contents up to N chunks ahead of the worker-dispatch cursor
|
||||
* is a wall-clock optimization (file I/O overlaps with worker compute),
|
||||
* not a graph-semantics change — the deferred-state aggregation still
|
||||
* runs in `chunkIdx` order so cross-chunk processors see deterministic
|
||||
* input regardless of file-read completion order.
|
||||
*/
|
||||
import { describe, it, expect, beforeEach, afterEach } from 'vitest';
|
||||
import fs from 'node:fs';
|
||||
import os from 'node:os';
|
||||
import path from 'node:path';
|
||||
|
||||
import { runChunkedParseAndResolve } from '../../src/core/ingestion/pipeline-phases/parse-impl.js';
|
||||
import { createKnowledgeGraph } from '../../src/core/graph/graph.js';
|
||||
|
||||
function scanned(repo: string, files: string[]) {
|
||||
return files.map((rel) => ({
|
||||
path: rel,
|
||||
size: fs.statSync(path.join(repo, rel)).size,
|
||||
}));
|
||||
}
|
||||
|
||||
describe('parse-impl chunk concurrency (U1)', () => {
|
||||
let repoPath = '';
|
||||
|
||||
beforeEach(() => {
|
||||
repoPath = fs.mkdtempSync(path.join(os.tmpdir(), 'parse-impl-chunk-concurrency-'));
|
||||
fs.writeFileSync(path.join(repoPath, 'a.ts'), 'export function foo() { return 1; }\n');
|
||||
fs.writeFileSync(
|
||||
path.join(repoPath, 'b.ts'),
|
||||
'import { foo } from "./a";\nexport function bar() { return foo(); }\n',
|
||||
);
|
||||
fs.writeFileSync(
|
||||
path.join(repoPath, 'c.ts'),
|
||||
'import { bar } from "./b";\nexport class Baz { run() { return bar(); } }\n',
|
||||
);
|
||||
});
|
||||
|
||||
afterEach(() => {
|
||||
if (repoPath && fs.existsSync(repoPath)) {
|
||||
fs.rmSync(repoPath, { recursive: true, force: true });
|
||||
}
|
||||
});
|
||||
|
||||
it('produces identical graph output across parseChunkConcurrency values', async () => {
|
||||
const files = ['a.ts', 'b.ts', 'c.ts'];
|
||||
const scan = scanned(repoPath, files);
|
||||
|
||||
const g1 = createKnowledgeGraph();
|
||||
await runChunkedParseAndResolve(g1, scan, files, files.length, repoPath, Date.now(), () => {}, {
|
||||
skipWorkers: true,
|
||||
parseChunkConcurrency: 1,
|
||||
});
|
||||
|
||||
const g2 = createKnowledgeGraph();
|
||||
await runChunkedParseAndResolve(g2, scan, files, files.length, repoPath, Date.now(), () => {}, {
|
||||
skipWorkers: true,
|
||||
parseChunkConcurrency: 2,
|
||||
});
|
||||
|
||||
// Same fixture under different concurrency values must produce the
|
||||
// same graph — F4 (wildcard-synthesis ordering): per-chunk results
|
||||
// merge in chunkIdx order regardless of file-read completion order,
|
||||
// so cross-chunk processors see deterministic input.
|
||||
expect(g2.nodeCount).toBe(g1.nodeCount);
|
||||
expect(g2.relationshipCount).toBe(g1.relationshipCount);
|
||||
});
|
||||
|
||||
it('accepts parseChunkConcurrency=1 (serial-equivalent) and produces the expected fixture symbols', async () => {
|
||||
const files = ['a.ts', 'b.ts', 'c.ts'];
|
||||
const graph = createKnowledgeGraph();
|
||||
await runChunkedParseAndResolve(
|
||||
graph,
|
||||
scanned(repoPath, files),
|
||||
files,
|
||||
files.length,
|
||||
repoPath,
|
||||
Date.now(),
|
||||
() => {},
|
||||
{ skipWorkers: true, parseChunkConcurrency: 1 },
|
||||
);
|
||||
// Exact assertions per DoD §2.7: pin specific symbols from the fixture
|
||||
// so a regression in either the chunk loop or the resolver surfaces
|
||||
// here instead of being masked by a bounds-only nodeCount check.
|
||||
const symbolNames = Array.from(graph.nodes.values()).map(
|
||||
(n) => (n.properties as { name?: string } | undefined)?.name,
|
||||
);
|
||||
expect(symbolNames.includes('foo')).toBe(true);
|
||||
expect(symbolNames.includes('bar')).toBe(true);
|
||||
expect(symbolNames.includes('Baz')).toBe(true);
|
||||
});
|
||||
|
||||
it('falls back to GITNEXUS_PARSE_CHUNK_CONCURRENCY env when option is undefined', async () => {
|
||||
const original = process.env.GITNEXUS_PARSE_CHUNK_CONCURRENCY;
|
||||
process.env.GITNEXUS_PARSE_CHUNK_CONCURRENCY = '3';
|
||||
try {
|
||||
const files = ['a.ts', 'b.ts', 'c.ts'];
|
||||
const graph = createKnowledgeGraph();
|
||||
await runChunkedParseAndResolve(
|
||||
graph,
|
||||
scanned(repoPath, files),
|
||||
files,
|
||||
files.length,
|
||||
repoPath,
|
||||
Date.now(),
|
||||
() => {},
|
||||
{ skipWorkers: true },
|
||||
);
|
||||
// Resolver reads the env when options.parseChunkConcurrency is
|
||||
// undefined. The env value (3) must produce the same fixture
|
||||
// symbols on this fixture as the other concurrency values do.
|
||||
const symbolNames = Array.from(graph.nodes.values()).map(
|
||||
(n) => (n.properties as { name?: string } | undefined)?.name,
|
||||
);
|
||||
expect(symbolNames.includes('foo')).toBe(true);
|
||||
expect(symbolNames.includes('bar')).toBe(true);
|
||||
expect(symbolNames.includes('Baz')).toBe(true);
|
||||
} finally {
|
||||
if (original === undefined) {
|
||||
delete process.env.GITNEXUS_PARSE_CHUNK_CONCURRENCY;
|
||||
} else {
|
||||
process.env.GITNEXUS_PARSE_CHUNK_CONCURRENCY = original;
|
||||
}
|
||||
}
|
||||
});
|
||||
});
|
||||
142
gitnexus/test/unit/parse-impl-deferred-extraction.test.ts
Normal file
142
gitnexus/test/unit/parse-impl-deferred-extraction.test.ts
Normal file
|
|
@ -0,0 +1,142 @@
|
|||
/**
|
||||
* U7 (B4 from PR #1693 review) — Deferred-extraction multi-chunk graph
|
||||
* equivalence.
|
||||
*
|
||||
* PR #1693 moved the per-chunk extraction passes (processImportsFromExtracted,
|
||||
* processHeritageFromExtracted, processRoutesFromExtracted,
|
||||
* synthesizeWildcardImportBindings, seedCrossFileReceiverTypes) out of the
|
||||
* per-chunk loop into a single end-of-loop pass. Lane 4 of the production-
|
||||
* readiness review proved the reorder is observably equivalent for every
|
||||
* processor under the worker path — but the existing suite never asserted
|
||||
* cross-chunk graph equivalence, which lets a future refactor that
|
||||
* accidentally tightens the per-chunk vs end-of-loop coupling break
|
||||
* cross-chunk import / heritage / call resolution silently.
|
||||
*
|
||||
* This file forces multi-chunk parsing on a small fixture by setting
|
||||
* `GITNEXUS_CHUNK_BYTE_BUDGET` low BEFORE the parse-impl module loads
|
||||
* (the budget is captured at module load, not per call — that's U14 from
|
||||
* Phase 2). Module re-loading is driven by `vi.resetModules()`. Then runs
|
||||
* the same fixture under a high budget (single chunk) and asserts the
|
||||
* two graphs are byte-identical: same node count, same relationship
|
||||
* count, same specific cross-chunk symbols.
|
||||
*/
|
||||
import { describe, it, expect, beforeEach, afterEach, vi } from 'vitest';
|
||||
import fs from 'node:fs';
|
||||
import os from 'node:os';
|
||||
import path from 'node:path';
|
||||
|
||||
const ORIGINAL_BUDGET = process.env.GITNEXUS_CHUNK_BYTE_BUDGET;
|
||||
|
||||
type Fixture = Record<string, string>;
|
||||
|
||||
/**
|
||||
* Cross-chunk fixture: file A defines, file B imports from A and re-exports,
|
||||
* file C imports from B and defines a class extending an A symbol. Forces
|
||||
* the resolver to chain imports across files — which the deferred-extraction
|
||||
* path must handle correctly under any chunking arrangement.
|
||||
*/
|
||||
const FIXTURE: Fixture = {
|
||||
'a.ts': 'export class Animal { speak(): string { return "noise"; } }\n',
|
||||
'b.ts':
|
||||
'import { Animal } from "./a";\nexport class Dog extends Animal { bark(): string { return "woof"; } }\n',
|
||||
'c.ts': 'import { Dog } from "./b";\nexport function makeDog(): Dog { return new Dog(); }\n',
|
||||
};
|
||||
|
||||
async function runWithBudget(budgetBytes: number): Promise<{
|
||||
nodeCount: number;
|
||||
relationshipCount: number;
|
||||
symbolNames: Set<string>;
|
||||
}> {
|
||||
process.env.GITNEXUS_CHUNK_BYTE_BUDGET = String(budgetBytes);
|
||||
vi.resetModules();
|
||||
const { runChunkedParseAndResolve } =
|
||||
await import('../../src/core/ingestion/pipeline-phases/parse-impl.js');
|
||||
const { createKnowledgeGraph } = await import('../../src/core/graph/graph.js');
|
||||
|
||||
const repoPath = fs.mkdtempSync(path.join(os.tmpdir(), 'parse-impl-multi-chunk-'));
|
||||
try {
|
||||
for (const [name, content] of Object.entries(FIXTURE)) {
|
||||
fs.writeFileSync(path.join(repoPath, name), content);
|
||||
}
|
||||
const files = Object.keys(FIXTURE);
|
||||
const scanned = files.map((rel) => ({
|
||||
path: rel,
|
||||
size: fs.statSync(path.join(repoPath, rel)).size,
|
||||
}));
|
||||
const graph = createKnowledgeGraph();
|
||||
await runChunkedParseAndResolve(
|
||||
graph,
|
||||
scanned,
|
||||
files,
|
||||
files.length,
|
||||
repoPath,
|
||||
Date.now(),
|
||||
() => {},
|
||||
{ skipWorkers: true },
|
||||
);
|
||||
const symbolNames = new Set<string>();
|
||||
for (const node of graph.nodes.values()) {
|
||||
const name = (node.properties as { name?: string } | undefined)?.name;
|
||||
if (typeof name === 'string') symbolNames.add(name);
|
||||
}
|
||||
return {
|
||||
nodeCount: graph.nodeCount,
|
||||
relationshipCount: graph.relationshipCount,
|
||||
symbolNames,
|
||||
};
|
||||
} finally {
|
||||
if (fs.existsSync(repoPath)) {
|
||||
fs.rmSync(repoPath, { recursive: true, force: true });
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
describe('parse-impl deferred-extraction multi-chunk equivalence (U7 / B4)', () => {
|
||||
beforeEach(() => {
|
||||
// Fresh module cache for every test so the GITNEXUS_CHUNK_BYTE_BUDGET
|
||||
// change made inside runWithBudget actually takes effect — parse-impl
|
||||
// captures the budget at module load.
|
||||
vi.resetModules();
|
||||
});
|
||||
|
||||
afterEach(() => {
|
||||
if (ORIGINAL_BUDGET === undefined) {
|
||||
delete process.env.GITNEXUS_CHUNK_BYTE_BUDGET;
|
||||
} else {
|
||||
process.env.GITNEXUS_CHUNK_BYTE_BUDGET = ORIGINAL_BUDGET;
|
||||
}
|
||||
});
|
||||
|
||||
it('produces byte-identical graph under single-chunk (high budget) and multi-chunk (low budget) layouts', async () => {
|
||||
// 10 MB budget — three small files (well under 1 KB total) fit in one
|
||||
// chunk. This is the baseline against which the multi-chunk path is
|
||||
// compared.
|
||||
const single = await runWithBudget(10 * 1024 * 1024);
|
||||
|
||||
// 64-byte budget — small enough that each fixture file ends up in its
|
||||
// own chunk (a.ts is ~60 bytes, b.ts/c.ts are larger). Forces the
|
||||
// deferred-extraction path to handle cross-chunk imports + class
|
||||
// hierarchy.
|
||||
const multi = await runWithBudget(64);
|
||||
|
||||
// The load-bearing assertions for B4 — if these drift, the deferred
|
||||
// reorder is not observably equivalent and someone has to investigate.
|
||||
expect(multi.nodeCount).toBe(single.nodeCount);
|
||||
expect(multi.relationshipCount).toBe(single.relationshipCount);
|
||||
});
|
||||
|
||||
it('resolves cross-chunk class symbols under the multi-chunk layout', async () => {
|
||||
// The multi-chunk path must still produce graph nodes for the symbols
|
||||
// declared across the three files. If chunking breaks resolution,
|
||||
// `Dog` (defined in b.ts but importing Animal from a.ts) or
|
||||
// `makeDog` (in c.ts, importing Dog from b.ts) would silently
|
||||
// disappear from the graph.
|
||||
const multi = await runWithBudget(64);
|
||||
|
||||
expect(multi.symbolNames.has('Animal')).toBe(true);
|
||||
expect(multi.symbolNames.has('Dog')).toBe(true);
|
||||
expect(multi.symbolNames.has('makeDog')).toBe(true);
|
||||
expect(multi.symbolNames.has('speak')).toBe(true);
|
||||
expect(multi.symbolNames.has('bark')).toBe(true);
|
||||
});
|
||||
});
|
||||
147
gitnexus/test/unit/parse-impl-env-reads.test.ts
Normal file
147
gitnexus/test/unit/parse-impl-env-reads.test.ts
Normal file
|
|
@ -0,0 +1,147 @@
|
|||
/**
|
||||
* U14 (F7 architectural from PR #1693 review) — Function-scope env reads
|
||||
* in parse-impl.
|
||||
*
|
||||
* Pre-U14, `CHUNK_BYTE_BUDGET` was a module-load IIFE constant that
|
||||
* captured `GITNEXUS_CHUNK_BYTE_BUDGET` once and froze the value for
|
||||
* the module's lifetime. That defeated `PipelineOptions.chunkByteBudget`
|
||||
* (silently no-op'd because the body read the frozen constant) AND
|
||||
* forced tests to use `vi.resetModules` to vary the chunk layout (see
|
||||
* the U7 deferred-extraction test and the U6 multi-chunk integration
|
||||
* test for examples of the workaround).
|
||||
*
|
||||
* After U14:
|
||||
* - Option present -> option wins (per-call, no env / no vi.resetModules)
|
||||
* - Option absent -> env wins (back-compat)
|
||||
* - Both absent -> built-in 2 MB default
|
||||
*
|
||||
* This file pins all three resolution branches, plus the behavioral
|
||||
* invariant the workaround was masking: two back-to-back runs in the
|
||||
* same vitest worker process can use DIFFERENT `chunkByteBudget` values
|
||||
* and observe DIFFERENT chunking on the same fixture WITHOUT needing
|
||||
* `vi.resetModules` between them.
|
||||
*/
|
||||
import { describe, it, expect, beforeEach, afterEach } from 'vitest';
|
||||
import fs from 'node:fs';
|
||||
import os from 'node:os';
|
||||
import path from 'node:path';
|
||||
|
||||
import { runChunkedParseAndResolve } from '../../src/core/ingestion/pipeline-phases/parse-impl.js';
|
||||
import { createKnowledgeGraph } from '../../src/core/graph/graph.js';
|
||||
|
||||
const ORIGINAL_BUDGET = process.env.GITNEXUS_CHUNK_BYTE_BUDGET;
|
||||
|
||||
type Fixture = Record<string, string>;
|
||||
|
||||
function makeRepo(fixture: Fixture): string {
|
||||
const dir = fs.mkdtempSync(path.join(os.tmpdir(), 'parse-impl-env-reads-'));
|
||||
for (const [name, content] of Object.entries(fixture)) {
|
||||
fs.writeFileSync(path.join(dir, name), content);
|
||||
}
|
||||
return dir;
|
||||
}
|
||||
|
||||
function scanned(repo: string, files: string[]) {
|
||||
return files.map((rel) => ({
|
||||
path: rel,
|
||||
size: fs.statSync(path.join(repo, rel)).size,
|
||||
}));
|
||||
}
|
||||
|
||||
/**
|
||||
* Capture every per-chunk progress message emitted during a run.
|
||||
* parse-impl emits one per chunk in the "Parsing chunk X/Y" form, so
|
||||
* counting unique chunk indices in the captured stream is a stable
|
||||
* proxy for the number of chunks the loop actually produced. Avoids
|
||||
* exposing internal counter state from parse-impl.
|
||||
*/
|
||||
async function countChunksFromProgress(
|
||||
repoPath: string,
|
||||
files: string[],
|
||||
options?: { chunkByteBudget?: number },
|
||||
): Promise<number> {
|
||||
const scan = scanned(repoPath, files);
|
||||
const graph = createKnowledgeGraph();
|
||||
const chunkIndices = new Set<string>();
|
||||
await runChunkedParseAndResolve(
|
||||
graph,
|
||||
scan,
|
||||
files,
|
||||
files.length,
|
||||
repoPath,
|
||||
Date.now(),
|
||||
(p) => {
|
||||
if (typeof p.message !== 'string') return;
|
||||
const m = /Parsing chunk (\d+)\/(\d+)/.exec(p.message);
|
||||
if (m !== null) chunkIndices.add(`${m[1]}/${m[2]}`);
|
||||
},
|
||||
{ skipWorkers: true, ...options },
|
||||
);
|
||||
return chunkIndices.size;
|
||||
}
|
||||
|
||||
describe('parse-impl chunkByteBudget resolution (U14 / F7)', () => {
|
||||
let repoPath = '';
|
||||
|
||||
beforeEach(() => {
|
||||
repoPath = makeRepo({
|
||||
'a.ts': 'export const A = 1;\n',
|
||||
'b.ts': 'export const B = 2;\n',
|
||||
'c.ts': 'export const C = 3;\n',
|
||||
});
|
||||
});
|
||||
|
||||
afterEach(() => {
|
||||
if (repoPath && fs.existsSync(repoPath)) {
|
||||
fs.rmSync(repoPath, { recursive: true, force: true });
|
||||
}
|
||||
if (ORIGINAL_BUDGET === undefined) {
|
||||
delete process.env.GITNEXUS_CHUNK_BYTE_BUDGET;
|
||||
} else {
|
||||
process.env.GITNEXUS_CHUNK_BYTE_BUDGET = ORIGINAL_BUDGET;
|
||||
}
|
||||
});
|
||||
|
||||
it('option-first: PipelineOptions.chunkByteBudget overrides the env var', async () => {
|
||||
// Force the env to a HUGE value that would normally collapse the
|
||||
// fixture to a single chunk; pass a SMALL option that produces 3
|
||||
// chunks. If the option wins, we observe 3 chunks; if env wins, 1.
|
||||
process.env.GITNEXUS_CHUNK_BYTE_BUDGET = String(10 * 1024 * 1024);
|
||||
const chunks = await countChunksFromProgress(repoPath, ['a.ts', 'b.ts', 'c.ts'], {
|
||||
chunkByteBudget: 8,
|
||||
});
|
||||
expect(chunks).toBe(3);
|
||||
});
|
||||
|
||||
it('env-fallback: GITNEXUS_CHUNK_BYTE_BUDGET is honored when the option is absent', async () => {
|
||||
process.env.GITNEXUS_CHUNK_BYTE_BUDGET = '8';
|
||||
const chunks = await countChunksFromProgress(repoPath, ['a.ts', 'b.ts', 'c.ts']);
|
||||
expect(chunks).toBe(3);
|
||||
});
|
||||
|
||||
it('default-fallback: large built-in budget keeps the fixture in a single chunk', async () => {
|
||||
// Both option and env unset → falls through to DEFAULT_CHUNK_BYTE_BUDGET
|
||||
// (2 MB). The fixture totals well under that, so exactly one chunk.
|
||||
delete process.env.GITNEXUS_CHUNK_BYTE_BUDGET;
|
||||
const chunks = await countChunksFromProgress(repoPath, ['a.ts', 'b.ts', 'c.ts']);
|
||||
expect(chunks).toBe(1);
|
||||
});
|
||||
|
||||
it('per-call: two back-to-back runs with different option values observe their own values, not the previous call', async () => {
|
||||
// The behavioral invariant U14 restores: a long-running host
|
||||
// (eval-server, MCP daemon) calling runChunkedParseAndResolve twice
|
||||
// with different chunkByteBudget values gets the value it passed,
|
||||
// not whatever the first call set (pre-U14, the module-load IIFE
|
||||
// froze the value at import — the option was a silent no-op).
|
||||
const files = ['a.ts', 'b.ts', 'c.ts'];
|
||||
delete process.env.GITNEXUS_CHUNK_BYTE_BUDGET;
|
||||
const small = await countChunksFromProgress(repoPath, files, {
|
||||
chunkByteBudget: 8,
|
||||
});
|
||||
const large = await countChunksFromProgress(repoPath, files, {
|
||||
chunkByteBudget: 10 * 1024 * 1024,
|
||||
});
|
||||
expect(small).toBe(3);
|
||||
expect(large).toBe(1);
|
||||
});
|
||||
});
|
||||
|
|
@ -141,10 +141,13 @@ describe('parse-impl sequential fallback cleanup (U6)', () => {
|
|||
() => {},
|
||||
{ skipWorkers: true },
|
||||
);
|
||||
// Happy path — should return a BindingAccumulator and clear astCache at
|
||||
// least once (per-chunk + finally).
|
||||
// Happy path — should return a BindingAccumulator and clear astCache
|
||||
// a deterministic number of times. The 2-file fixture goes through
|
||||
// the chunk loop's clear (twice: one inside the chunk body, one in
|
||||
// the chunk's finally), plus the outer pipeline finally (twice
|
||||
// again for sequential's two-phase teardown). Total: 4.
|
||||
expect(result.bindingAccumulator).toBeDefined();
|
||||
expect(spies.astCacheClearCalls).toBeGreaterThanOrEqual(1);
|
||||
expect(spies.astCacheClearCalls).toBe(4);
|
||||
// finalize() on a BindingAccumulator makes it read-only; appending after
|
||||
// finalize throws. We use that to prove finalize actually ran.
|
||||
expect(() =>
|
||||
|
|
@ -175,8 +178,10 @@ describe('parse-impl sequential fallback cleanup (U6)', () => {
|
|||
),
|
||||
).rejects.toThrow(/injected readFileContents failure/);
|
||||
|
||||
// Finally-block must have cleared astCache at least once on the error path.
|
||||
expect(spies.astCacheClearCalls).toBeGreaterThan(clearsBefore);
|
||||
// Error path 1 (readFileContents throws mid-fallback): the chunk's
|
||||
// finally still fires (clears once) and the outer pipeline finally
|
||||
// also fires (clears once). Delta from the happy path is exactly 2.
|
||||
expect(spies.astCacheClearCalls - clearsBefore).toBe(2);
|
||||
});
|
||||
|
||||
it('error path: processCalls throws in fallback loop — cleanup still runs', async () => {
|
||||
|
|
@ -198,7 +203,10 @@ describe('parse-impl sequential fallback cleanup (U6)', () => {
|
|||
),
|
||||
).rejects.toThrow(/injected processCalls failure/);
|
||||
|
||||
// astCache.clear() must have run in the finally block.
|
||||
expect(spies.astCacheClearCalls).toBeGreaterThan(clearsBefore);
|
||||
// Error path 2 (processCalls throws in fallback loop): the chunk's
|
||||
// body clear runs before processCalls throws, the chunk's finally
|
||||
// clear also runs, and the outer pipeline finally clear runs.
|
||||
// Delta from the happy path is exactly 3.
|
||||
expect(spies.astCacheClearCalls - clearsBefore).toBe(3);
|
||||
});
|
||||
});
|
||||
|
|
|
|||
132
gitnexus/test/unit/parse-impl-progress-monotonic.test.ts
Normal file
132
gitnexus/test/unit/parse-impl-progress-monotonic.test.ts
Normal file
|
|
@ -0,0 +1,132 @@
|
|||
/**
|
||||
* U4 (M2) — Monotonic progress through the parse + deferred-extraction phases.
|
||||
*
|
||||
* Before this fix, parse-impl emitted `percent: 82` for every progress
|
||||
* update during the deferred resolution stages (imports, heritage, routes,
|
||||
* calls). The UI sat at 82 for the duration of the deferred work — on real
|
||||
* repos, several seconds to minutes — looking exactly like a hang, which is
|
||||
* the user-facing symptom PR #1693 set out to fix.
|
||||
*
|
||||
* After M2, parse phase covers 20-70 and deferred extraction covers 70-95
|
||||
* across four labelled sub-bands. This test runs `runChunkedParseAndResolve`
|
||||
* on a small temp repo via the deterministic sequential-fallback path
|
||||
* (`skipWorkers: true`) and asserts the recorded percent stream is strictly
|
||||
* non-decreasing AND reaches the deferred band (>=70) before returning.
|
||||
*/
|
||||
import { describe, it, expect, beforeEach, afterEach } from 'vitest';
|
||||
import fs from 'node:fs';
|
||||
import os from 'node:os';
|
||||
import path from 'node:path';
|
||||
|
||||
import { runChunkedParseAndResolve } from '../../src/core/ingestion/pipeline-phases/parse-impl.js';
|
||||
import { createKnowledgeGraph } from '../../src/core/graph/graph.js';
|
||||
|
||||
function makeTempRepo(files: Record<string, string>): string {
|
||||
const dir = fs.mkdtempSync(path.join(os.tmpdir(), 'parse-impl-progress-'));
|
||||
for (const [rel, content] of Object.entries(files)) {
|
||||
const abs = path.join(dir, rel);
|
||||
fs.mkdirSync(path.dirname(abs), { recursive: true });
|
||||
fs.writeFileSync(abs, content);
|
||||
}
|
||||
return dir;
|
||||
}
|
||||
|
||||
function scanned(repo: string, files: string[]) {
|
||||
return files.map((rel) => ({
|
||||
path: rel,
|
||||
size: fs.statSync(path.join(repo, rel)).size,
|
||||
}));
|
||||
}
|
||||
|
||||
describe('parse-impl progress monotonicity (U4 M2)', () => {
|
||||
let repoPath = '';
|
||||
|
||||
beforeEach(() => {
|
||||
repoPath = makeTempRepo({
|
||||
'a.ts': `export function foo() { return 1; }\n`,
|
||||
'b.ts': `import { foo } from './a';\nexport function bar() { return foo(); }\n`,
|
||||
'c.ts': `import { bar } from './b';\nexport class Baz { run() { return bar(); } }\n`,
|
||||
});
|
||||
});
|
||||
|
||||
afterEach(() => {
|
||||
if (repoPath && fs.existsSync(repoPath)) {
|
||||
fs.rmSync(repoPath, { recursive: true, force: true });
|
||||
}
|
||||
});
|
||||
|
||||
it('emits a strictly non-decreasing percent stream and reaches the deferred band', async () => {
|
||||
const graph = createKnowledgeGraph();
|
||||
const files = ['a.ts', 'b.ts', 'c.ts'];
|
||||
const percents: number[] = [];
|
||||
|
||||
await runChunkedParseAndResolve(
|
||||
graph,
|
||||
scanned(repoPath, files),
|
||||
files,
|
||||
files.length,
|
||||
repoPath,
|
||||
Date.now(),
|
||||
(p) => {
|
||||
if (typeof p.percent === 'number') percents.push(p.percent);
|
||||
},
|
||||
{ skipWorkers: true },
|
||||
);
|
||||
|
||||
// The stream MUST be non-empty (a regression that stops emitting
|
||||
// progress should fail this test). Express via exact-equality
|
||||
// negation rather than a bound.
|
||||
expect(percents).not.toEqual([]);
|
||||
|
||||
// Strict monotonic non-decreasing across the whole stream. Direct
|
||||
// comparison — the previous `Math.max(prev, cur)` form resolved to
|
||||
// `expect(cur).toBe(cur)` which is a tautology.
|
||||
for (let i = 1; i < percents.length; i++) {
|
||||
if (percents[i] < percents[i - 1]) {
|
||||
throw new Error(
|
||||
`progress regressed: percents[${i}]=${percents[i]} < percents[${i - 1}]=${percents[i - 1]}`,
|
||||
);
|
||||
}
|
||||
}
|
||||
|
||||
// The parse phase advances through 20-70; the deferred extraction band
|
||||
// covers 70-95. On a 3-file fixture with imports + heritage + calls,
|
||||
// we should observe at least one percent value in the 70-95 band so the
|
||||
// monotonic-advance behavior is exercised, not just the parse half.
|
||||
const reachedDeferredBand = percents.some((p) => p >= 70 && p <= 95);
|
||||
expect(reachedDeferredBand).toBe(true);
|
||||
|
||||
// On this 3-file fixture in skipWorkers mode the deferred band
|
||||
// advances exactly to 70 (the start of the band). The orchestrator
|
||||
// (run-analyze) drives 70-100 itself once cross-chunk extraction
|
||||
// finishes. Pinning the exact observed value catches both an
|
||||
// upper-bound regression (anything >70 would unexpectedly land in
|
||||
// the band) AND a lower-bound regression (anything <70 would mean
|
||||
// the parse phase didn't complete).
|
||||
expect(percents[percents.length - 1]).toBe(70);
|
||||
});
|
||||
|
||||
it('emits percent 95 (not 82) when there are no parseable files to skip past the parse band', async () => {
|
||||
const graph = createKnowledgeGraph();
|
||||
// No parseable files: empty scanned list, empty parseable list.
|
||||
const percents: number[] = [];
|
||||
|
||||
await runChunkedParseAndResolve(
|
||||
graph,
|
||||
[],
|
||||
[],
|
||||
0,
|
||||
repoPath,
|
||||
Date.now(),
|
||||
(p) => {
|
||||
if (typeof p.percent === 'number') percents.push(p.percent);
|
||||
},
|
||||
{ skipWorkers: true },
|
||||
);
|
||||
|
||||
// The early-return path must emit 95 (the new post-deferred ceiling),
|
||||
// not the stale 82 it used before M2 — otherwise downstream phases
|
||||
// would visibly regress percent on the next update.
|
||||
expect(percents).toEqual([95]);
|
||||
});
|
||||
});
|
||||
|
|
@ -1,44 +1,145 @@
|
|||
/**
|
||||
* processParsing — worker-pool error handling contract.
|
||||
*
|
||||
* U20 design pivot (PR #1693): there is NO sequential-parser fallback
|
||||
* when the worker pool fails. The pool's resilience layers (respawn
|
||||
* budget, circuit breaker, quarantine, slot-attribution, cumulative
|
||||
* timeout) are the sole contract for handling worker failures. When
|
||||
* those exhaust, `processParsing` propagates the error to the caller
|
||||
* — `runChunkedParseAndResolve` and the analyze entry point above it.
|
||||
*
|
||||
* This file replaces the previous sequential-fallback tests (which
|
||||
* asserted that processParsing caught WorkerPoolDispatchError and
|
||||
* called processParsingSequential on the remaining files). The new
|
||||
* contract is "errors propagate, no rescue."
|
||||
*
|
||||
* Why removing the fallback was the right call:
|
||||
* - The fallback ran the SAME tree-sitter parser the worker just
|
||||
* crashed on, but on the main thread. A native crash (SIGSEGV
|
||||
* from a tree-sitter binding) in the worker would re-trigger the
|
||||
* same SIGSEGV on the main thread, killing the whole analyze
|
||||
* instead of just the worker.
|
||||
* - It hid pool failures behind a degraded-but-completing analyze
|
||||
* run, making them harder to detect and diagnose.
|
||||
* - U2's chunk-cache write suppression keeps cross-run retry
|
||||
* working: a quarantined file's chunk stays uncached, so the
|
||||
* next analyze with a fresh pool gets another chance.
|
||||
*/
|
||||
import { describe, expect, it, vi } from 'vitest';
|
||||
import { createASTCache } from '../../src/core/ingestion/ast-cache.js';
|
||||
import { processParsing } from '../../src/core/ingestion/parsing-processor.js';
|
||||
import type { WorkerPool } from '../../src/core/ingestion/workers/worker-pool.js';
|
||||
import { WorkerPoolDispatchError } from '../../src/core/ingestion/workers/worker-pool.js';
|
||||
import { createKnowledgeGraph } from '../../src/core/graph/graph.js';
|
||||
import { createSymbolTable } from '../../src/core/ingestion/model/symbol-table.js';
|
||||
|
||||
describe('processParsing worker fallback', () => {
|
||||
it('continues sequentially with visible progress when the worker pool times out', async () => {
|
||||
describe('processParsing — worker-pool error propagation (U20)', () => {
|
||||
it('propagates a raw worker-pool throw to the caller without rescuing', async () => {
|
||||
const graph = createKnowledgeGraph();
|
||||
const progressCounts: number[] = [];
|
||||
const progressDetails: string[] = [];
|
||||
const workerPool: WorkerPool = {
|
||||
size: 1,
|
||||
dispatch: vi.fn(async (_items, onProgress?: (filesProcessed: number) => void) => {
|
||||
onProgress?.(1);
|
||||
throw new Error('injected worker idle timeout');
|
||||
dispatch: vi.fn(async () => {
|
||||
throw new Error('replacement worker failed');
|
||||
}),
|
||||
terminate: vi.fn(async () => undefined),
|
||||
};
|
||||
|
||||
const result = await processParsing(
|
||||
await expect(
|
||||
processParsing(
|
||||
graph,
|
||||
[{ path: 'src/a.ts', content: 'export function a() { return 1; }\n' }],
|
||||
createSymbolTable(),
|
||||
createASTCache(),
|
||||
createASTCache(),
|
||||
() => {},
|
||||
workerPool,
|
||||
),
|
||||
).rejects.toThrow('replacement worker failed');
|
||||
|
||||
// No sequential fallback ran, so the graph stays empty.
|
||||
expect(
|
||||
graph.nodes.some((node) => node.label === 'Function' && node.properties.name === 'a'),
|
||||
).toBe(false);
|
||||
});
|
||||
|
||||
it('propagates WorkerPoolDispatchError with quarantinedPaths intact', async () => {
|
||||
const graph = createKnowledgeGraph();
|
||||
const workerPool: WorkerPool = {
|
||||
size: 1,
|
||||
dispatch: vi.fn(async () => {
|
||||
throw new WorkerPoolDispatchError(
|
||||
'Worker pool circuit breaker tripped: 2 consecutive failures on slot 0',
|
||||
['src/poison.ts'],
|
||||
);
|
||||
}),
|
||||
terminate: vi.fn(async () => undefined),
|
||||
};
|
||||
|
||||
const rejection = processParsing(
|
||||
graph,
|
||||
[{ path: 'src/a.ts', content: 'export function a() { return 1; }\n' }],
|
||||
[
|
||||
{ path: 'src/poison.ts', content: 'export function poison() { return 0; }\n' },
|
||||
{ path: 'src/a.ts', content: 'export function a() { return 1; }\n' },
|
||||
],
|
||||
createSymbolTable(),
|
||||
createASTCache(),
|
||||
createASTCache(),
|
||||
(current, _total, detail) => {
|
||||
progressCounts.push(current);
|
||||
() => {},
|
||||
workerPool,
|
||||
);
|
||||
|
||||
await expect(rejection).rejects.toBeInstanceOf(WorkerPoolDispatchError);
|
||||
const err = await rejection.catch((e) => e as WorkerPoolDispatchError);
|
||||
expect(err.quarantinedPaths).toEqual(['src/poison.ts']);
|
||||
|
||||
// No sequential fallback ran for either file. The caller (analyze
|
||||
// entry point) is responsible for surfacing this as a hard
|
||||
// failure.
|
||||
expect(
|
||||
graph.nodes.some((node) => node.label === 'Function' && node.properties.name === 'a'),
|
||||
).toBe(false);
|
||||
expect(
|
||||
graph.nodes.some((node) => node.label === 'Function' && node.properties.name === 'poison'),
|
||||
).toBe(false);
|
||||
});
|
||||
|
||||
it('worker-path returns successfully when the pool reports a quarantine snapshot without throwing', async () => {
|
||||
// Quarantine is a normal session-scoped signal: the pool filters
|
||||
// quarantined files out of dispatch, returns the survivors'
|
||||
// results, and reports the cumulative set via getQuarantinedPaths.
|
||||
// processParsing's worker-path completes successfully on this
|
||||
// partial-coverage signal — the quarantined file is missing from
|
||||
// the graph, but no error is thrown. The chunk-loop caller uses
|
||||
// the quarantine snapshot to decide whether to write the chunk
|
||||
// cache (U2 in parse-impl.ts).
|
||||
const graph = createKnowledgeGraph();
|
||||
const workerPool: WorkerPool = {
|
||||
size: 1,
|
||||
dispatch: vi.fn(async () => []),
|
||||
terminate: vi.fn(async () => undefined),
|
||||
getQuarantinedPaths: () => ['src/poison.ts'],
|
||||
};
|
||||
|
||||
const progressDetails: string[] = [];
|
||||
const result = await processParsing(
|
||||
graph,
|
||||
[
|
||||
{ path: 'src/poison.ts', content: 'export function poison() { return 0; }\n' },
|
||||
{ path: 'src/a.ts', content: 'export function a() { return 1; }\n' },
|
||||
],
|
||||
createSymbolTable(),
|
||||
createASTCache(),
|
||||
createASTCache(),
|
||||
(_current, _total, detail) => {
|
||||
progressDetails.push(detail);
|
||||
},
|
||||
workerPool,
|
||||
);
|
||||
|
||||
expect(result).toBeNull();
|
||||
expect(progressDetails).toContain(
|
||||
'Sequential fallback after worker issue: injected worker idle timeout',
|
||||
);
|
||||
expect(progressCounts).toEqual([...progressCounts].sort((a, b) => a - b));
|
||||
expect(
|
||||
graph.nodes.some((node) => node.label === 'Function' && node.properties.name === 'a'),
|
||||
).toBe(true);
|
||||
// Worker path returned successfully (not null — null was the
|
||||
// pre-U20 sentinel for "ran sequential fallback"). The progress
|
||||
// log surfaces the quarantine count for operator visibility.
|
||||
expect(result).not.toBeNull();
|
||||
expect(progressDetails).toContain('1 worker-quarantined file(s) skipped');
|
||||
});
|
||||
});
|
||||
|
|
|
|||
243
gitnexus/test/unit/run-analyze-fts-repair.test.ts
Normal file
243
gitnexus/test/unit/run-analyze-fts-repair.test.ts
Normal file
|
|
@ -0,0 +1,243 @@
|
|||
import fs from 'fs/promises';
|
||||
import { afterEach, describe, expect, it, vi } from 'vitest';
|
||||
import { getStoragePaths, saveMeta } from '../../src/storage/repo-manager.js';
|
||||
import { createTempDir } from '../helpers/test-db.js';
|
||||
|
||||
const SIMULATED_MISSING_FTS_INDEX_NAME = 'File.file_fts';
|
||||
const PLACEHOLDER_GRAPH_STORE_CONTENT = 'fixture';
|
||||
|
||||
const createPlaceholderGraphStore = async (lbugPath: string): Promise<void> => {
|
||||
// Repair mode gates on existence before `initLbug` takes over open/validate.
|
||||
// A placeholder file is enough to exercise this preflight branch.
|
||||
await fs.writeFile(lbugPath, PLACEHOLDER_GRAPH_STORE_CONTENT);
|
||||
};
|
||||
|
||||
const escapeForRegex = (value: string): string => value.replace(/[.*+?^${}()|[\]\\]/g, '\\$&');
|
||||
|
||||
describe('runFullAnalysis FTS repair and verification failure paths', () => {
|
||||
afterEach(() => {
|
||||
vi.doUnmock('../../src/core/lbug/lbug-adapter.js');
|
||||
vi.doUnmock('../../src/core/search/fts-indexes.js');
|
||||
vi.doUnmock('../../src/core/ingestion/pipeline.js');
|
||||
vi.resetModules();
|
||||
vi.clearAllMocks();
|
||||
});
|
||||
|
||||
it('fails repair mode when no base meta exists', async () => {
|
||||
const tmpRepo = await createTempDir('gitnexus-run-analyze-repair-no-meta-');
|
||||
try {
|
||||
const { runFullAnalysis } = await import('../../src/core/run-analyze.js');
|
||||
|
||||
await expect(
|
||||
runFullAnalysis(
|
||||
tmpRepo.dbPath,
|
||||
{ repairFts: true },
|
||||
{
|
||||
onProgress: () => {},
|
||||
},
|
||||
),
|
||||
).rejects.toThrow(/has not been analyzed yet/i);
|
||||
} finally {
|
||||
await tmpRepo.cleanup();
|
||||
}
|
||||
});
|
||||
|
||||
it('fails repair mode when graph store is missing', async () => {
|
||||
const tmpRepo = await createTempDir('gitnexus-run-analyze-repair-missing-store-');
|
||||
try {
|
||||
const { storagePath, lbugPath } = getStoragePaths(tmpRepo.dbPath);
|
||||
await fs.mkdir(storagePath, { recursive: true });
|
||||
await saveMeta(storagePath, {
|
||||
repoPath: tmpRepo.dbPath,
|
||||
lastCommit: '',
|
||||
indexedAt: new Date().toISOString(),
|
||||
stats: {},
|
||||
});
|
||||
|
||||
const { runFullAnalysis } = await import('../../src/core/run-analyze.js');
|
||||
|
||||
await expect(
|
||||
runFullAnalysis(
|
||||
tmpRepo.dbPath,
|
||||
{ repairFts: true },
|
||||
{
|
||||
onProgress: () => {},
|
||||
},
|
||||
),
|
||||
).rejects.toThrow(new RegExp(`graph store at ${escapeForRegex(lbugPath)} is missing`));
|
||||
} finally {
|
||||
await tmpRepo.cleanup();
|
||||
}
|
||||
});
|
||||
|
||||
it('fails repair mode when graph store path is not a file', async () => {
|
||||
const tmpRepo = await createTempDir('gitnexus-run-analyze-repair-store-not-file-');
|
||||
try {
|
||||
const { storagePath, lbugPath } = getStoragePaths(tmpRepo.dbPath);
|
||||
await fs.mkdir(storagePath, { recursive: true });
|
||||
await saveMeta(storagePath, {
|
||||
repoPath: tmpRepo.dbPath,
|
||||
lastCommit: '',
|
||||
indexedAt: new Date().toISOString(),
|
||||
stats: {},
|
||||
});
|
||||
await fs.mkdir(lbugPath, { recursive: true });
|
||||
|
||||
const { runFullAnalysis } = await import('../../src/core/run-analyze.js');
|
||||
|
||||
await expect(
|
||||
runFullAnalysis(
|
||||
tmpRepo.dbPath,
|
||||
{ repairFts: true },
|
||||
{
|
||||
onProgress: () => {},
|
||||
},
|
||||
),
|
||||
).rejects.toThrow(
|
||||
new RegExp(
|
||||
`graph store at ${escapeForRegex(lbugPath)} is a directory \\(expected a file\\)`,
|
||||
),
|
||||
);
|
||||
} finally {
|
||||
await tmpRepo.cleanup();
|
||||
}
|
||||
});
|
||||
|
||||
it('fails repair mode when FTS verify still reports missing indexes', async () => {
|
||||
const closeLbugMock = vi.fn(async () => undefined);
|
||||
vi.doMock('../../src/core/lbug/lbug-adapter.js', () => ({
|
||||
initLbug: vi.fn(async () => undefined),
|
||||
loadGraphToLbug: vi.fn(async () => undefined),
|
||||
getLbugStats: vi.fn(async () => ({})),
|
||||
executeQuery: vi.fn(async () => []),
|
||||
executeWithReusedStatement: vi.fn(async () => []),
|
||||
closeLbug: closeLbugMock,
|
||||
loadCachedEmbeddings: vi.fn(async () => ({ embeddingNodeIds: new Set(), embeddings: [] })),
|
||||
deleteNodesForFile: vi.fn(async () => undefined),
|
||||
deleteAllCommunitiesAndProcesses: vi.fn(async () => undefined),
|
||||
queryImporters: vi.fn(async () => []),
|
||||
}));
|
||||
vi.doMock('../../src/core/search/fts-indexes.js', () => ({
|
||||
createSearchFTSIndexes: vi.fn(async () => undefined),
|
||||
verifySearchFTSIndexes: vi.fn(async () => [SIMULATED_MISSING_FTS_INDEX_NAME]),
|
||||
}));
|
||||
|
||||
const tmpRepo = await createTempDir('gitnexus-run-analyze-repair-verify-fail-');
|
||||
try {
|
||||
const { storagePath, lbugPath } = getStoragePaths(tmpRepo.dbPath);
|
||||
await fs.mkdir(storagePath, { recursive: true });
|
||||
await saveMeta(storagePath, {
|
||||
repoPath: tmpRepo.dbPath,
|
||||
lastCommit: '',
|
||||
indexedAt: new Date().toISOString(),
|
||||
stats: {},
|
||||
});
|
||||
await createPlaceholderGraphStore(lbugPath);
|
||||
|
||||
const { runFullAnalysis } = await import('../../src/core/run-analyze.js');
|
||||
|
||||
await expect(
|
||||
runFullAnalysis(
|
||||
tmpRepo.dbPath,
|
||||
{ repairFts: true },
|
||||
{
|
||||
onProgress: () => {},
|
||||
},
|
||||
),
|
||||
).rejects.toThrow(/FTS repair failed - missing indexes after rebuild/i);
|
||||
expect(closeLbugMock).toHaveBeenCalled();
|
||||
} finally {
|
||||
await tmpRepo.cleanup();
|
||||
}
|
||||
});
|
||||
|
||||
it('surfaces extension-unavailable errors from FTS index creation in repair mode', async () => {
|
||||
vi.doMock('../../src/core/lbug/lbug-adapter.js', () => ({
|
||||
initLbug: vi.fn(async () => undefined),
|
||||
loadGraphToLbug: vi.fn(async () => undefined),
|
||||
getLbugStats: vi.fn(async () => ({})),
|
||||
executeQuery: vi.fn(async () => []),
|
||||
executeWithReusedStatement: vi.fn(async () => []),
|
||||
closeLbug: vi.fn(async () => undefined),
|
||||
loadCachedEmbeddings: vi.fn(async () => ({ embeddingNodeIds: new Set(), embeddings: [] })),
|
||||
deleteNodesForFile: vi.fn(async () => undefined),
|
||||
deleteAllCommunitiesAndProcesses: vi.fn(async () => undefined),
|
||||
queryImporters: vi.fn(async () => []),
|
||||
}));
|
||||
vi.doMock('../../src/core/search/fts-indexes.js', () => ({
|
||||
createSearchFTSIndexes: vi.fn(async () => {
|
||||
throw new Error('FTS extension unavailable');
|
||||
}),
|
||||
verifySearchFTSIndexes: vi.fn(async () => []),
|
||||
}));
|
||||
|
||||
const tmpRepo = await createTempDir('gitnexus-run-analyze-repair-extension-fail-');
|
||||
try {
|
||||
const { storagePath, lbugPath } = getStoragePaths(tmpRepo.dbPath);
|
||||
await fs.mkdir(storagePath, { recursive: true });
|
||||
await saveMeta(storagePath, {
|
||||
repoPath: tmpRepo.dbPath,
|
||||
lastCommit: '',
|
||||
indexedAt: new Date().toISOString(),
|
||||
stats: {},
|
||||
});
|
||||
await createPlaceholderGraphStore(lbugPath);
|
||||
|
||||
const { runFullAnalysis } = await import('../../src/core/run-analyze.js');
|
||||
|
||||
await expect(
|
||||
runFullAnalysis(
|
||||
tmpRepo.dbPath,
|
||||
{ repairFts: true },
|
||||
{
|
||||
onProgress: () => {},
|
||||
},
|
||||
),
|
||||
).rejects.toThrow(/FTS extension unavailable/i);
|
||||
} finally {
|
||||
await tmpRepo.cleanup();
|
||||
}
|
||||
});
|
||||
|
||||
it('fails full analyze when FTS verification reports missing indexes after creation', async () => {
|
||||
vi.doMock('../../src/core/lbug/lbug-adapter.js', () => ({
|
||||
initLbug: vi.fn(async () => undefined),
|
||||
loadGraphToLbug: vi.fn(async () => undefined),
|
||||
getLbugStats: vi.fn(async () => ({ nodes: 0, edges: 0, communities: 0, processes: 0 })),
|
||||
executeQuery: vi.fn(async () => []),
|
||||
executeWithReusedStatement: vi.fn(async () => []),
|
||||
closeLbug: vi.fn(async () => undefined),
|
||||
loadCachedEmbeddings: vi.fn(async () => ({ embeddingNodeIds: new Set(), embeddings: [] })),
|
||||
deleteNodesForFile: vi.fn(async () => undefined),
|
||||
deleteAllCommunitiesAndProcesses: vi.fn(async () => undefined),
|
||||
queryImporters: vi.fn(async () => []),
|
||||
}));
|
||||
vi.doMock('../../src/core/search/fts-indexes.js', () => ({
|
||||
createSearchFTSIndexes: vi.fn(async () => undefined),
|
||||
verifySearchFTSIndexes: vi.fn(async () => ['Function.function_fts']),
|
||||
}));
|
||||
vi.doMock('../../src/core/ingestion/pipeline.js', () => ({
|
||||
runPipelineFromRepo: vi.fn(async (repoPath: string) => ({
|
||||
repoPath,
|
||||
// Full-analyze path only needs `forEachNode` before the FTS verify guard.
|
||||
graph: { forEachNode: () => undefined },
|
||||
})),
|
||||
}));
|
||||
|
||||
const tmpRepo = await createTempDir('gitnexus-run-analyze-full-verify-fail-');
|
||||
try {
|
||||
const { runFullAnalysis } = await import('../../src/core/run-analyze.js');
|
||||
await expect(
|
||||
runFullAnalysis(
|
||||
tmpRepo.dbPath,
|
||||
{ force: true },
|
||||
{
|
||||
onProgress: () => {},
|
||||
},
|
||||
),
|
||||
).rejects.toThrow(/FTS verification failed - missing indexes after analyze/i);
|
||||
} finally {
|
||||
await tmpRepo.cleanup();
|
||||
}
|
||||
});
|
||||
});
|
||||
|
|
@ -19,7 +19,7 @@ import {
|
|||
evaluateForTest,
|
||||
getRegistrySize,
|
||||
} from '../../../../src/core/ingestion/languages/cpp/constraint-filter.js';
|
||||
import type { ArityVerdict, SymbolDefinition } from 'gitnexus-shared';
|
||||
import type { ArityVerdict, ParameterTypeClass, SymbolDefinition } from 'gitnexus-shared';
|
||||
|
||||
function templateConstraintsFor(src: string): CppConstraintPayload | undefined {
|
||||
const matches = emitCppScopeCaptures(src, 'test.cpp');
|
||||
|
|
@ -201,11 +201,26 @@ describe('evaluate — Kleene 3-valued truth table', () => {
|
|||
// ─── Section 3: Predicate registry ─────────────────────────────────────────
|
||||
|
||||
describe('Tier-A predicate registry', () => {
|
||||
it('registry size is exactly 4 (surface-guard against accidental adds)', () => {
|
||||
expect(getRegistrySize()).toBe(4);
|
||||
it('registry size is exactly 11 (surface-guard against accidental adds)', () => {
|
||||
expect(getRegistrySize()).toBe(11);
|
||||
});
|
||||
|
||||
function verdict(name: string, args: string[], argumentTypes: readonly string[]): ArityVerdict {
|
||||
const shape = (
|
||||
base: string,
|
||||
indirection: ParameterTypeClass['indirection'] = 'value',
|
||||
cv: ParameterTypeClass['cv'] = 'none',
|
||||
pointerDepth = indirection === 'pointer' ? 1 : 0,
|
||||
): ParameterTypeClass => ({ base, cv, indirection, pointerDepth });
|
||||
|
||||
function verdict(
|
||||
name: string,
|
||||
args: string[],
|
||||
argumentTypes: readonly string[],
|
||||
opts: {
|
||||
readonly argumentTypeClasses?: readonly ParameterTypeClass[];
|
||||
readonly parameterTypeClasses?: readonly ParameterTypeClass[];
|
||||
} = {},
|
||||
): ArityVerdict {
|
||||
const payload: CppConstraintPayload = {
|
||||
templateParams: args,
|
||||
paramArgIndex: Object.fromEntries(args.map((a, i) => [a, i])),
|
||||
|
|
@ -216,8 +231,16 @@ describe('Tier-A predicate registry', () => {
|
|||
filePath: 'x.cpp',
|
||||
type: 'Function',
|
||||
templateConstraints: payload,
|
||||
...(opts.parameterTypeClasses !== undefined
|
||||
? { parameterTypeClasses: opts.parameterTypeClasses }
|
||||
: {}),
|
||||
};
|
||||
return cppConstraintCompatibility({ arity: argumentTypes.length }, def, { argumentTypes });
|
||||
return cppConstraintCompatibility({ arity: argumentTypes.length }, def, {
|
||||
argumentTypes,
|
||||
...(opts.argumentTypeClasses !== undefined
|
||||
? { argumentTypeClasses: opts.argumentTypeClasses }
|
||||
: {}),
|
||||
});
|
||||
}
|
||||
|
||||
it('is_integral_v matches int, rejects double, unknown for blank', () => {
|
||||
|
|
@ -257,6 +280,117 @@ describe('Tier-A predicate registry', () => {
|
|||
expect(verdict('is_same_v', ['A', 'B'], ['char', 'int'])).toBe('incompatible');
|
||||
});
|
||||
|
||||
it('is_void_v matches void, rejects int, unknown for blank', () => {
|
||||
expect(verdict('is_void_v', ['T'], ['void'])).toBe('compatible');
|
||||
expect(verdict('is_void_v', ['T'], ['int'])).toBe('incompatible');
|
||||
expect(verdict('is_void_v', ['T'], [''])).toBe('unknown');
|
||||
});
|
||||
|
||||
it('is_enum_v matches known enum tokens, rejects class, unknown for blank', () => {
|
||||
expect(
|
||||
verdict('is_enum_v', ['T'], ['Color'], {
|
||||
argumentTypeClasses: [shape('enum:Color')],
|
||||
parameterTypeClasses: [shape('T')],
|
||||
}),
|
||||
).toBe('compatible');
|
||||
expect(verdict('is_enum_v', ['T'], ['Widget'])).toBe('incompatible');
|
||||
expect(verdict('is_enum_v', ['T'], [''])).toBe('unknown');
|
||||
});
|
||||
|
||||
it('is_class_v matches class-like tokens, rejects primitives, unknown for blank', () => {
|
||||
expect(verdict('is_class_v', ['T'], ['Widget'])).toBe('compatible');
|
||||
expect(verdict('is_class_v', ['T'], ['int'])).toBe('incompatible');
|
||||
expect(verdict('is_class_v', ['T'], [''])).toBe('unknown');
|
||||
});
|
||||
|
||||
it('is_pointer_v uses the argument type-class sidecar conservatively', () => {
|
||||
expect(
|
||||
verdict('is_pointer_v', ['T'], ['int'], {
|
||||
argumentTypeClasses: [shape('int', 'pointer')],
|
||||
parameterTypeClasses: [shape('T')],
|
||||
}),
|
||||
).toBe('compatible');
|
||||
expect(
|
||||
verdict('is_pointer_v', ['T'], ['int'], {
|
||||
argumentTypeClasses: [shape('int')],
|
||||
parameterTypeClasses: [shape('T')],
|
||||
}),
|
||||
).toBe('incompatible');
|
||||
expect(verdict('is_pointer_v', ['T'], ['int'])).toBe('unknown');
|
||||
expect(
|
||||
verdict('is_pointer_v', ['T'], ['int'], {
|
||||
argumentTypeClasses: [shape('int', 'unknown', 'none')],
|
||||
parameterTypeClasses: [shape('T')],
|
||||
}),
|
||||
).toBe('unknown');
|
||||
});
|
||||
|
||||
it('is_reference_v uses the argument type-class sidecar conservatively', () => {
|
||||
expect(
|
||||
verdict('is_reference_v', ['T'], ['int'], {
|
||||
argumentTypeClasses: [shape('int', 'lvalue-ref')],
|
||||
parameterTypeClasses: [shape('T')],
|
||||
}),
|
||||
).toBe('compatible');
|
||||
expect(
|
||||
verdict('is_reference_v', ['T'], ['int'], {
|
||||
argumentTypeClasses: [shape('int')],
|
||||
parameterTypeClasses: [shape('T')],
|
||||
}),
|
||||
).toBe('incompatible');
|
||||
expect(verdict('is_reference_v', ['T'], ['int'])).toBe('unknown');
|
||||
expect(
|
||||
verdict('is_reference_v', ['T'], ['int'], {
|
||||
argumentTypeClasses: [shape('int', 'unknown', 'none')],
|
||||
parameterTypeClasses: [shape('T')],
|
||||
}),
|
||||
).toBe('unknown');
|
||||
});
|
||||
|
||||
it('is_const_v and is_volatile_v read top-level cv from the sidecar conservatively', () => {
|
||||
expect(
|
||||
verdict('is_const_v', ['T'], ['int'], {
|
||||
argumentTypeClasses: [shape('int', 'value', 'const')],
|
||||
parameterTypeClasses: [shape('T')],
|
||||
}),
|
||||
).toBe('compatible');
|
||||
expect(
|
||||
verdict('is_const_v', ['T'], ['int'], {
|
||||
argumentTypeClasses: [shape('int')],
|
||||
parameterTypeClasses: [shape('T')],
|
||||
}),
|
||||
).toBe('incompatible');
|
||||
expect(verdict('is_const_v', ['T'], ['int'])).toBe('unknown');
|
||||
expect(
|
||||
verdict('is_volatile_v', ['T'], ['int'], {
|
||||
argumentTypeClasses: [shape('int', 'value', 'volatile')],
|
||||
parameterTypeClasses: [shape('T')],
|
||||
}),
|
||||
).toBe('compatible');
|
||||
expect(verdict('is_volatile_v', ['T'], ['int'])).toBe('unknown');
|
||||
expect(
|
||||
verdict('is_const_v', ['T'], ['int'], {
|
||||
argumentTypeClasses: [shape('int', 'pointer', 'const')],
|
||||
parameterTypeClasses: [shape('T')],
|
||||
}),
|
||||
).toBe('unknown');
|
||||
expect(
|
||||
verdict('is_const_v', ['T'], ['int'], {
|
||||
argumentTypeClasses: [shape('int', 'value', 'unknown')],
|
||||
parameterTypeClasses: [shape('T')],
|
||||
}),
|
||||
).toBe('unknown');
|
||||
});
|
||||
|
||||
it('shape-sensitive predicates stay unknown when T is not the whole parameter type', () => {
|
||||
expect(
|
||||
verdict('is_pointer_v', ['T'], ['int'], {
|
||||
argumentTypeClasses: [shape('int', 'pointer')],
|
||||
parameterTypeClasses: [shape('T', 'pointer')],
|
||||
}),
|
||||
).toBe('unknown');
|
||||
});
|
||||
|
||||
it('unregistered predicate yields unknown (monotonicity)', () => {
|
||||
expect(verdict('__not_in_registry__', ['T'], ['int'])).toBe('unknown');
|
||||
});
|
||||
|
|
|
|||
|
|
@ -0,0 +1,111 @@
|
|||
import { describe, expect, it } from 'vitest';
|
||||
import type { ParameterTypeClass, SymbolDefinition } from 'gitnexus-shared';
|
||||
import { cppConversionRank } from '../../../../src/core/ingestion/languages/cpp/conversion-rank.js';
|
||||
import { narrowOverloadCandidates } from '../../../../src/core/ingestion/scope-resolution/passes/overload-narrowing.js';
|
||||
|
||||
const value = (base: string): ParameterTypeClass => ({
|
||||
base,
|
||||
cv: 'none',
|
||||
indirection: 'value',
|
||||
pointerDepth: 0,
|
||||
});
|
||||
|
||||
const pointer = (base: string): ParameterTypeClass => ({
|
||||
base,
|
||||
cv: 'none',
|
||||
indirection: 'pointer',
|
||||
pointerDepth: 1,
|
||||
});
|
||||
|
||||
const ellipsis = (): ParameterTypeClass => ({
|
||||
base: '...',
|
||||
cv: 'unknown',
|
||||
indirection: 'unknown',
|
||||
pointerDepth: 0,
|
||||
});
|
||||
|
||||
const mkDef = (
|
||||
nodeId: string,
|
||||
parameterTypes: readonly string[],
|
||||
parameterTypeClasses: readonly ParameterTypeClass[],
|
||||
): SymbolDefinition => ({
|
||||
nodeId,
|
||||
filePath: 'service.cpp',
|
||||
type: 'Method',
|
||||
parameterCount: parameterTypes.includes('...') ? undefined : parameterTypes.length,
|
||||
requiredParameterCount: parameterTypes.includes('...')
|
||||
? parameterTypes.indexOf('...')
|
||||
: parameterTypes.length,
|
||||
parameterTypes: [...parameterTypes],
|
||||
parameterTypeClasses: [...parameterTypeClasses],
|
||||
});
|
||||
|
||||
describe('cppConversionRank pointer/nullptr/ellipsis ranks (#1637)', () => {
|
||||
it('ranks nullptr -> T* ahead of nullptr -> bool', () => {
|
||||
expect(cppConversionRank('null', 'int', value('null'), pointer('int'))).toBe(2);
|
||||
expect(cppConversionRank('null', 'bool', value('null'), value('bool'))).toBe(3);
|
||||
});
|
||||
|
||||
it('ranks pointer -> bool and pointer -> void* as standard conversions', () => {
|
||||
expect(cppConversionRank('int', 'bool', pointer('int'), value('bool'))).toBe(2);
|
||||
expect(cppConversionRank('int', 'void', pointer('int'), pointer('void'))).toBe(2);
|
||||
});
|
||||
|
||||
it('keeps pointer exact matches shape-aware', () => {
|
||||
expect(cppConversionRank('int', 'int', pointer('int'), pointer('int'))).toBe(0);
|
||||
expect(cppConversionRank('int', 'int', value('int'), pointer('int'))).toBe(Infinity);
|
||||
});
|
||||
|
||||
it('ranks ellipsis as the worst viable conversion', () => {
|
||||
expect(cppConversionRank('int', '...', value('int'), ellipsis())).toBe(4);
|
||||
});
|
||||
});
|
||||
|
||||
describe('narrowOverloadCandidates with C++ pointer-rank sidecars (#1637)', () => {
|
||||
it('selects pointer overload for nullptr over bool overload', () => {
|
||||
const byPointer = mkDef('f:intptr', ['int'], [pointer('int')]);
|
||||
const byBool = mkDef('f:bool', ['bool'], [value('bool')]);
|
||||
|
||||
const result = narrowOverloadCandidates([byPointer, byBool], 1, ['null'], {
|
||||
argumentTypeClasses: [value('null')],
|
||||
conversionRankFn: cppConversionRank,
|
||||
});
|
||||
|
||||
expect(result.map((d) => d.nodeId)).toEqual(['f:intptr']);
|
||||
});
|
||||
|
||||
it('does not treat normalized value and pointer types as exact matches', () => {
|
||||
const byPointer = mkDef('f:intptr', ['int'], [pointer('int')]);
|
||||
const byBool = mkDef('f:bool', ['bool'], [value('bool')]);
|
||||
|
||||
const result = narrowOverloadCandidates([byPointer, byBool], 1, ['int'], {
|
||||
argumentTypeClasses: [value('int')],
|
||||
conversionRankFn: cppConversionRank,
|
||||
});
|
||||
|
||||
expect(result.map((d) => d.nodeId)).toEqual(['f:bool']);
|
||||
});
|
||||
|
||||
it('selects fixed-arity overload over ellipsis', () => {
|
||||
const exact = mkDef('g:int-int', ['int', 'int'], [value('int'), value('int')]);
|
||||
const variadic = mkDef('g:ellipsis', ['int', '...'], [value('int'), ellipsis()]);
|
||||
|
||||
const result = narrowOverloadCandidates([exact, variadic], 2, ['int', 'int'], {
|
||||
argumentTypeClasses: [value('int'), value('int')],
|
||||
conversionRankFn: cppConversionRank,
|
||||
});
|
||||
|
||||
expect(result.map((d) => d.nodeId)).toEqual(['g:int-int']);
|
||||
});
|
||||
|
||||
it('keeps an ellipsis overload viable when it is the only match', () => {
|
||||
const variadic = mkDef('log:ellipsis', ['int', '...'], [value('int'), ellipsis()]);
|
||||
|
||||
const result = narrowOverloadCandidates([variadic], 3, ['int', 'int', 'double'], {
|
||||
argumentTypeClasses: [value('int'), value('int'), value('double')],
|
||||
conversionRankFn: cppConversionRank,
|
||||
});
|
||||
|
||||
expect(result.map((d) => d.nodeId)).toEqual(['log:ellipsis']);
|
||||
});
|
||||
});
|
||||
|
|
@ -0,0 +1,147 @@
|
|||
/**
|
||||
* U8 (B5 from PR #1693 review) — TS capture ancestor-walk regression coverage.
|
||||
*
|
||||
* PR #1693 rewrote `emitTsScopeCaptures` to walk from each captured node's
|
||||
* own subtree (`findSelfOrAncestorOfType[s]` + `pickFirstNode`) instead of
|
||||
* re-scanning the whole AST from the root via `findNodeAtRange`. Lane 4 of
|
||||
* the production-readiness review proved the new path is semantically
|
||||
* equivalent to the prior range-based lookup for every anchor the TS
|
||||
* query emits — but the existing `typescript-captures.test.ts` doesn't
|
||||
* pin the specific sharp edges that an over-aggressive ancestor walk
|
||||
* would break. This file does.
|
||||
*
|
||||
* Each test exercises a capture class whose anchor type is one the
|
||||
* rewrite explicitly handles: `call_expression`, `new_expression`,
|
||||
* `import_statement` / `export_statement`, `call_expression` with
|
||||
* `import` (dynamic), and the JSX-anchored `@reference.call.*` form
|
||||
* that must NOT synthesize an outer call. Assertions are exact `.toBe(N)`
|
||||
* per DoD §2.7.
|
||||
*/
|
||||
import { describe, it, expect } from 'vitest';
|
||||
import { emitTsScopeCaptures } from '../../../../src/core/ingestion/languages/typescript/captures.js';
|
||||
|
||||
function countMatches(src: string, predicate: (tags: string[]) => boolean): number {
|
||||
const matches = emitTsScopeCaptures(src, 'test.ts');
|
||||
return matches.filter((m) => predicate(Object.keys(m))).length;
|
||||
}
|
||||
|
||||
function countMatchesTsx(src: string, predicate: (tags: string[]) => boolean): number {
|
||||
// TSX-specific query path: file extension drives query selection inside
|
||||
// emitTsScopeCaptures. Without `.tsx` the JSX call-anchored variants
|
||||
// never fire, so this test would silently pass on the TypeScript-only
|
||||
// path instead of exercising the JSX-anchor case the rewrite cares about.
|
||||
const matches = emitTsScopeCaptures(src, 'test.tsx');
|
||||
return matches.filter((m) => predicate(Object.keys(m))).length;
|
||||
}
|
||||
|
||||
describe('captures.ts ancestor-walk rewrite (U8 / B5)', () => {
|
||||
it('member call `obj.foo()` emits exactly one @reference.call.member capture', () => {
|
||||
// call_expression anchor → self in ancestor walk. Baseline case the
|
||||
// rewrite must preserve: a direct member call captures once via
|
||||
// @reference.call.member, not zero (would mean ancestor walk lost
|
||||
// the anchor) and not two (would mean the walk over-emitted).
|
||||
const count = countMatches('function run(obj: { foo(): void }): void { obj.foo(); }', (t) =>
|
||||
t.includes('@reference.call.member'),
|
||||
);
|
||||
expect(count).toBe(1);
|
||||
});
|
||||
|
||||
it('dynamic import gets decomposed to @import.statement with kind=dynamic', () => {
|
||||
// import(...) is captured by the raw query as @import.dynamic
|
||||
// (call_expression with `import` function). captures.ts then
|
||||
// decomposes it via splitImportStatement, which re-emits a normalized
|
||||
// @import.statement match with @import.kind set to "dynamic" — so the
|
||||
// central extractor sees ONE uniform import shape regardless of
|
||||
// static-vs-dynamic. The raw @import.dynamic tag does NOT survive
|
||||
// into the output stream after decomposition.
|
||||
const matches = emitTsScopeCaptures(
|
||||
'async function load() { const mod = await import("./helper"); return mod; }',
|
||||
'test.ts',
|
||||
);
|
||||
const dyn = matches.filter(
|
||||
(m) => '@import.statement' in m && m['@import.kind']?.text === 'dynamic',
|
||||
);
|
||||
expect(dyn.length).toBe(1);
|
||||
// The decomposed source-string capture carries the literal with
|
||||
// surrounding quotes stripped (the decomposer normalizes before
|
||||
// emitting the synthetic @import.source marker — downstream
|
||||
// consumers receive the bare module specifier).
|
||||
expect(dyn[0]['@import.source']?.text).toBe('./helper');
|
||||
});
|
||||
|
||||
it('JSX <Foo /> emits a call.free capture (TSX-only query path) but no arity synthesis', () => {
|
||||
// Both jsx_self_closing_element and jsx_opening_element with an
|
||||
// identifier name pattern in the TSX query emit @reference.call.free
|
||||
// (see query.ts lines 899-905). Lane 4 of the production-readiness
|
||||
// review documented the design: the capture surfaces so downstream
|
||||
// consumers know the JSX component is referenced, but arity
|
||||
// synthesis (findSelfOrAncestorOfType('call_expression')) returns
|
||||
// null because the anchor is a jsx_*_element, NOT a call_expression
|
||||
// — so no @declaration.parameter-count is attached. Pre-rewrite, the
|
||||
// range-based lookup also returned null. This pins both: the capture
|
||||
// exists AND arity is not synthesized.
|
||||
const matches = emitTsScopeCaptures('function App() { return <Foo />; }', 'test.tsx');
|
||||
const jsxCalls = matches.filter((m) => '@reference.call.free' in m);
|
||||
expect(jsxCalls.length).toBe(1);
|
||||
// No spurious arity synthesis on the JSX-anchored capture. If a
|
||||
// future refactor "helpfully" walks JSX → call_expression, this
|
||||
// assertion fails and the implementer revisits the design.
|
||||
expect('@declaration.parameter-count' in jsxCalls[0]).toBe(false);
|
||||
});
|
||||
|
||||
it('constructor call `new Foo(1, 2)` emits exactly one @reference.call.constructor capture', () => {
|
||||
// new_expression anchor → self in ancestor walk.
|
||||
const count = countMatches(
|
||||
'class Foo { constructor(_a: number, _b: number) {} }\nconst x = new Foo(1, 2);',
|
||||
(t) => t.includes('@reference.call.constructor'),
|
||||
);
|
||||
expect(count).toBe(1);
|
||||
});
|
||||
|
||||
it('named import `import { foo } from "./a"` emits exactly one @import.statement', () => {
|
||||
const count = countMatches('import { foo } from "./a";\nconst x = foo();', (t) =>
|
||||
t.includes('@import.statement'),
|
||||
);
|
||||
expect(count).toBe(1);
|
||||
});
|
||||
|
||||
it('namespace import `import * as ns from "./a"` emits exactly one @import.statement', () => {
|
||||
const count = countMatches('import * as ns from "./a";\nconst x = ns.foo();', (t) =>
|
||||
t.includes('@import.statement'),
|
||||
);
|
||||
expect(count).toBe(1);
|
||||
});
|
||||
|
||||
it('re-export `export { foo } from "./a"` emits exactly one @import.statement', () => {
|
||||
// export_statement with a source string IS captured as @import.statement
|
||||
// (re-exports are pseudo-imports for graph purposes). Ancestor-walk
|
||||
// targets `['import_statement', 'export_statement']` so the
|
||||
// export_statement anchor matches itself.
|
||||
const count = countMatches('export { foo } from "./a";', (t) =>
|
||||
t.includes('@import.statement'),
|
||||
);
|
||||
expect(count).toBe(1);
|
||||
});
|
||||
|
||||
it('class method override produces a method capture per class (no collapse, no over-capture)', () => {
|
||||
// Two run() methods, one per class, both must capture distinctly.
|
||||
// Pins that the FUNCTION_DECL_TAGS / @declaration.method ancestor-walk
|
||||
// doesn't accidentally merge override sites onto the parent class.
|
||||
const count = countMatches(
|
||||
'class Base { run(): number { return 1; } }\nclass Child extends Base { run(): number { return 2; } }',
|
||||
(t) => t.includes('@declaration.method'),
|
||||
);
|
||||
expect(count).toBe(2);
|
||||
});
|
||||
|
||||
it('member read `obj.foo` (no call) emits exactly one @reference.read.member capture', () => {
|
||||
// member_expression anchor → self in ancestor walk. Read-only access
|
||||
// (not followed by call parens) is the relevant case — a member that
|
||||
// IS called is captured under @reference.call.member instead.
|
||||
const count = countMatches(
|
||||
'function run(obj: { foo: number }): number { return obj.foo; }',
|
||||
(t) => t.includes('@reference.read.member'),
|
||||
);
|
||||
expect(count).toBe(1);
|
||||
});
|
||||
});
|
||||
Some files were not shown because too many files have changed in this diff Show more
Loading…
Add table
Reference in a new issue